diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/README.md b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/README.md new file mode 100644 index 0000000000000000000000000000000000000000..31ad27793e34783faabc222adf98691fb396a0d8 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/README.md @@ -0,0 +1,3 @@ +# Schedulers + +For more information on the schedulers, please refer to the [docs](https://huggingface.co/docs/diffusers/api/schedulers/overview). \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/__init__.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..4ca47f19bc837cfe5d9a75ef51dbd5bff0421696 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/__init__.py @@ -0,0 +1,224 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from typing import TYPE_CHECKING + +from ..utils import ( + DIFFUSERS_SLOW_IMPORT, + OptionalDependencyNotAvailable, + _LazyModule, + get_objects_from_module, + is_flax_available, + is_scipy_available, + is_torch_available, + is_torchsde_available, +) + + +_dummy_modules = {} +_import_structure = {} + +try: + if not is_torch_available(): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import dummy_pt_objects # noqa F403 + + _dummy_modules.update(get_objects_from_module(dummy_pt_objects)) + +else: + _import_structure["deprecated"] = ["KarrasVeScheduler", "ScoreSdeVpScheduler"] + _import_structure["scheduling_amused"] = ["AmusedScheduler"] + _import_structure["scheduling_consistency_decoder"] = ["ConsistencyDecoderScheduler"] + _import_structure["scheduling_consistency_models"] = ["CMStochasticIterativeScheduler"] + _import_structure["scheduling_ddim"] = ["DDIMScheduler"] + _import_structure["scheduling_ddim_cogvideox"] = ["CogVideoXDDIMScheduler"] + _import_structure["scheduling_ddim_inverse"] = ["DDIMInverseScheduler"] + _import_structure["scheduling_ddim_parallel"] = ["DDIMParallelScheduler"] + _import_structure["scheduling_ddpm"] = ["DDPMScheduler"] + _import_structure["scheduling_ddpm_parallel"] = ["DDPMParallelScheduler"] + _import_structure["scheduling_ddpm_wuerstchen"] = ["DDPMWuerstchenScheduler"] + _import_structure["scheduling_deis_multistep"] = ["DEISMultistepScheduler"] + _import_structure["scheduling_dpm_cogvideox"] = ["CogVideoXDPMScheduler"] + _import_structure["scheduling_dpmsolver_multistep"] = ["DPMSolverMultistepScheduler"] + _import_structure["scheduling_dpmsolver_multistep_inverse"] = ["DPMSolverMultistepInverseScheduler"] + _import_structure["scheduling_dpmsolver_singlestep"] = ["DPMSolverSinglestepScheduler"] + _import_structure["scheduling_edm_dpmsolver_multistep"] = ["EDMDPMSolverMultistepScheduler"] + _import_structure["scheduling_edm_euler"] = ["EDMEulerScheduler"] + _import_structure["scheduling_euler_ancestral_discrete"] = ["EulerAncestralDiscreteScheduler"] + _import_structure["scheduling_euler_discrete"] = ["EulerDiscreteScheduler"] + _import_structure["scheduling_flow_match_euler_discrete"] = ["FlowMatchEulerDiscreteScheduler"] + _import_structure["scheduling_flow_match_heun_discrete"] = ["FlowMatchHeunDiscreteScheduler"] + _import_structure["scheduling_flow_match_lcm"] = ["FlowMatchLCMScheduler"] + _import_structure["scheduling_heun_discrete"] = ["HeunDiscreteScheduler"] + _import_structure["scheduling_ipndm"] = ["IPNDMScheduler"] + _import_structure["scheduling_k_dpm_2_ancestral_discrete"] = ["KDPM2AncestralDiscreteScheduler"] + _import_structure["scheduling_k_dpm_2_discrete"] = ["KDPM2DiscreteScheduler"] + _import_structure["scheduling_lcm"] = ["LCMScheduler"] + _import_structure["scheduling_pndm"] = ["PNDMScheduler"] + _import_structure["scheduling_repaint"] = ["RePaintScheduler"] + _import_structure["scheduling_sasolver"] = ["SASolverScheduler"] + _import_structure["scheduling_scm"] = ["SCMScheduler"] + _import_structure["scheduling_sde_ve"] = ["ScoreSdeVeScheduler"] + _import_structure["scheduling_tcd"] = ["TCDScheduler"] + _import_structure["scheduling_unclip"] = ["UnCLIPScheduler"] + _import_structure["scheduling_unipc_multistep"] = ["UniPCMultistepScheduler"] + _import_structure["scheduling_utils"] = ["AysSchedules", "KarrasDiffusionSchedulers", "SchedulerMixin"] + _import_structure["scheduling_vq_diffusion"] = ["VQDiffusionScheduler"] + +try: + if not is_flax_available(): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import dummy_flax_objects # noqa F403 + + _dummy_modules.update(get_objects_from_module(dummy_flax_objects)) + +else: + _import_structure["scheduling_ddim_flax"] = ["FlaxDDIMScheduler"] + _import_structure["scheduling_ddpm_flax"] = ["FlaxDDPMScheduler"] + _import_structure["scheduling_dpmsolver_multistep_flax"] = ["FlaxDPMSolverMultistepScheduler"] + _import_structure["scheduling_euler_discrete_flax"] = ["FlaxEulerDiscreteScheduler"] + _import_structure["scheduling_karras_ve_flax"] = ["FlaxKarrasVeScheduler"] + _import_structure["scheduling_lms_discrete_flax"] = ["FlaxLMSDiscreteScheduler"] + _import_structure["scheduling_pndm_flax"] = ["FlaxPNDMScheduler"] + _import_structure["scheduling_sde_ve_flax"] = ["FlaxScoreSdeVeScheduler"] + _import_structure["scheduling_utils_flax"] = [ + "FlaxKarrasDiffusionSchedulers", + "FlaxSchedulerMixin", + "FlaxSchedulerOutput", + "broadcast_to_shape_from_left", + ] + + +try: + if not (is_torch_available() and is_scipy_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import dummy_torch_and_scipy_objects # noqa F403 + + _dummy_modules.update(get_objects_from_module(dummy_torch_and_scipy_objects)) + +else: + _import_structure["scheduling_lms_discrete"] = ["LMSDiscreteScheduler"] + +try: + if not (is_torch_available() and is_torchsde_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import dummy_torch_and_torchsde_objects # noqa F403 + + _dummy_modules.update(get_objects_from_module(dummy_torch_and_torchsde_objects)) + +else: + _import_structure["scheduling_cosine_dpmsolver_multistep"] = ["CosineDPMSolverMultistepScheduler"] + _import_structure["scheduling_dpmsolver_sde"] = ["DPMSolverSDEScheduler"] + +if TYPE_CHECKING or DIFFUSERS_SLOW_IMPORT: + from ..utils import ( + OptionalDependencyNotAvailable, + is_flax_available, + is_scipy_available, + is_torch_available, + is_torchsde_available, + ) + + try: + if not is_torch_available(): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_pt_objects import * # noqa F403 + else: + from .deprecated import KarrasVeScheduler, ScoreSdeVpScheduler + from .scheduling_amused import AmusedScheduler + from .scheduling_consistency_decoder import ConsistencyDecoderScheduler + from .scheduling_consistency_models import CMStochasticIterativeScheduler + from .scheduling_ddim import DDIMScheduler + from .scheduling_ddim_cogvideox import CogVideoXDDIMScheduler + from .scheduling_ddim_inverse import DDIMInverseScheduler + from .scheduling_ddim_parallel import DDIMParallelScheduler + from .scheduling_ddpm import DDPMScheduler + from .scheduling_ddpm_parallel import DDPMParallelScheduler + from .scheduling_ddpm_wuerstchen import DDPMWuerstchenScheduler + from .scheduling_deis_multistep import DEISMultistepScheduler + from .scheduling_dpm_cogvideox import CogVideoXDPMScheduler + from .scheduling_dpmsolver_multistep import DPMSolverMultistepScheduler + from .scheduling_dpmsolver_multistep_inverse import DPMSolverMultistepInverseScheduler + from .scheduling_dpmsolver_singlestep import DPMSolverSinglestepScheduler + from .scheduling_edm_dpmsolver_multistep import EDMDPMSolverMultistepScheduler + from .scheduling_edm_euler import EDMEulerScheduler + from .scheduling_euler_ancestral_discrete import EulerAncestralDiscreteScheduler + from .scheduling_euler_discrete import EulerDiscreteScheduler + from .scheduling_flow_match_euler_discrete import FlowMatchEulerDiscreteScheduler + from .scheduling_flow_match_heun_discrete import FlowMatchHeunDiscreteScheduler + from .scheduling_flow_match_lcm import FlowMatchLCMScheduler + from .scheduling_heun_discrete import HeunDiscreteScheduler + from .scheduling_ipndm import IPNDMScheduler + from .scheduling_k_dpm_2_ancestral_discrete import KDPM2AncestralDiscreteScheduler + from .scheduling_k_dpm_2_discrete import KDPM2DiscreteScheduler + from .scheduling_lcm import LCMScheduler + from .scheduling_pndm import PNDMScheduler + from .scheduling_repaint import RePaintScheduler + from .scheduling_sasolver import SASolverScheduler + from .scheduling_scm import SCMScheduler + from .scheduling_sde_ve import ScoreSdeVeScheduler + from .scheduling_tcd import TCDScheduler + from .scheduling_unclip import UnCLIPScheduler + from .scheduling_unipc_multistep import UniPCMultistepScheduler + from .scheduling_utils import AysSchedules, KarrasDiffusionSchedulers, SchedulerMixin + from .scheduling_vq_diffusion import VQDiffusionScheduler + try: + if not is_flax_available(): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_flax_objects import * # noqa F403 + else: + from .scheduling_ddim_flax import FlaxDDIMScheduler + from .scheduling_ddpm_flax import FlaxDDPMScheduler + from .scheduling_dpmsolver_multistep_flax import FlaxDPMSolverMultistepScheduler + from .scheduling_euler_discrete_flax import FlaxEulerDiscreteScheduler + from .scheduling_karras_ve_flax import FlaxKarrasVeScheduler + from .scheduling_lms_discrete_flax import FlaxLMSDiscreteScheduler + from .scheduling_pndm_flax import FlaxPNDMScheduler + from .scheduling_sde_ve_flax import FlaxScoreSdeVeScheduler + from .scheduling_utils_flax import ( + FlaxKarrasDiffusionSchedulers, + FlaxSchedulerMixin, + FlaxSchedulerOutput, + broadcast_to_shape_from_left, + ) + + try: + if not (is_torch_available() and is_scipy_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_torch_and_scipy_objects import * # noqa F403 + else: + from .scheduling_lms_discrete import LMSDiscreteScheduler + + try: + if not (is_torch_available() and is_torchsde_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_torch_and_torchsde_objects import * # noqa F403 + else: + from .scheduling_cosine_dpmsolver_multistep import CosineDPMSolverMultistepScheduler + from .scheduling_dpmsolver_sde import DPMSolverSDEScheduler + +else: + import sys + + sys.modules[__name__] = _LazyModule(__name__, globals()["__file__"], _import_structure, module_spec=__spec__) + for name, value in _dummy_modules.items(): + setattr(sys.modules[__name__], name, value) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/deprecated/__init__.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/deprecated/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..479cf9bd568be320b60e87a831bf80835e9943f2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/deprecated/__init__.py @@ -0,0 +1,50 @@ +from typing import TYPE_CHECKING + +from ...utils import ( + DIFFUSERS_SLOW_IMPORT, + OptionalDependencyNotAvailable, + _LazyModule, + get_objects_from_module, + is_torch_available, + is_transformers_available, +) + + +_dummy_objects = {} +_import_structure = {} + +try: + if not (is_transformers_available() and is_torch_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ...utils import dummy_pt_objects # noqa F403 + + _dummy_objects.update(get_objects_from_module(dummy_pt_objects)) +else: + _import_structure["scheduling_karras_ve"] = ["KarrasVeScheduler"] + _import_structure["scheduling_sde_vp"] = ["ScoreSdeVpScheduler"] + +if TYPE_CHECKING or DIFFUSERS_SLOW_IMPORT: + try: + if not is_torch_available(): + raise OptionalDependencyNotAvailable() + + except OptionalDependencyNotAvailable: + from ...utils.dummy_pt_objects import * # noqa F403 + else: + from .scheduling_karras_ve import KarrasVeScheduler + from .scheduling_sde_vp import ScoreSdeVpScheduler + + +else: + import sys + + sys.modules[__name__] = _LazyModule( + __name__, + globals()["__file__"], + _import_structure, + module_spec=__spec__, + ) + + for name, value in _dummy_objects.items(): + setattr(sys.modules[__name__], name, value) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/deprecated/scheduling_karras_ve.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/deprecated/scheduling_karras_ve.py new file mode 100644 index 0000000000000000000000000000000000000000..57fd7e66879e74e923c5a46bd6c40335c1c28794 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/deprecated/scheduling_karras_ve.py @@ -0,0 +1,244 @@ +# Copyright 2024 NVIDIA and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import numpy as np +import torch + +from ...configuration_utils import ConfigMixin, register_to_config +from ...utils import BaseOutput +from ...utils.torch_utils import randn_tensor +from ..scheduling_utils import SchedulerMixin + + +@dataclass +class KarrasVeOutput(BaseOutput): + """ + Output class for the scheduler's step function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample (x_{t-1}) of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + derivative (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Derivative of predicted original image sample (x_0). + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample (x_{0}) based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + derivative: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +class KarrasVeScheduler(SchedulerMixin, ConfigMixin): + """ + A stochastic scheduler tailored to variance-expanding models. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + + + For more details on the parameters, see [Appendix E](https://huggingface.co/papers/2206.00364). The grid search + values used to find the optimal `{s_noise, s_churn, s_min, s_max}` for a specific model are described in Table 5 of + the paper. + + + + Args: + sigma_min (`float`, defaults to 0.02): + The minimum noise magnitude. + sigma_max (`float`, defaults to 100): + The maximum noise magnitude. + s_noise (`float`, defaults to 1.007): + The amount of additional noise to counteract loss of detail during sampling. A reasonable range is [1.000, + 1.011]. + s_churn (`float`, defaults to 80): + The parameter controlling the overall amount of stochasticity. A reasonable range is [0, 100]. + s_min (`float`, defaults to 0.05): + The start value of the sigma range to add noise (enable stochasticity). A reasonable range is [0, 10]. + s_max (`float`, defaults to 50): + The end value of the sigma range to add noise. A reasonable range is [0.2, 80]. + """ + + order = 2 + + @register_to_config + def __init__( + self, + sigma_min: float = 0.02, + sigma_max: float = 100, + s_noise: float = 1.007, + s_churn: float = 80, + s_min: float = 0.05, + s_max: float = 50, + ): + # standard deviation of the initial noise distribution + self.init_noise_sigma = sigma_max + + # setable values + self.num_inference_steps: int = None + self.timesteps: np.IntTensor = None + self.schedule: torch.Tensor = None # sigma(t_i) + + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + self.num_inference_steps = num_inference_steps + timesteps = np.arange(0, self.num_inference_steps)[::-1].copy() + self.timesteps = torch.from_numpy(timesteps).to(device) + schedule = [ + ( + self.config.sigma_max**2 + * (self.config.sigma_min**2 / self.config.sigma_max**2) ** (i / (num_inference_steps - 1)) + ) + for i in self.timesteps + ] + self.schedule = torch.tensor(schedule, dtype=torch.float32, device=device) + + def add_noise_to_input( + self, sample: torch.Tensor, sigma: float, generator: Optional[torch.Generator] = None + ) -> Tuple[torch.Tensor, float]: + """ + Explicit Langevin-like "churn" step of adding noise to the sample according to a `gamma_i ≥ 0` to reach a + higher noise level `sigma_hat = sigma_i + gamma_i*sigma_i`. + + Args: + sample (`torch.Tensor`): + The input sample. + sigma (`float`): + generator (`torch.Generator`, *optional*): + A random number generator. + """ + if self.config.s_min <= sigma <= self.config.s_max: + gamma = min(self.config.s_churn / self.num_inference_steps, 2**0.5 - 1) + else: + gamma = 0 + + # sample eps ~ N(0, S_noise^2 * I) + eps = self.config.s_noise * randn_tensor(sample.shape, generator=generator).to(sample.device) + sigma_hat = sigma + gamma * sigma + sample_hat = sample + ((sigma_hat**2 - sigma**2) ** 0.5 * eps) + + return sample_hat, sigma_hat + + def step( + self, + model_output: torch.Tensor, + sigma_hat: float, + sigma_prev: float, + sample_hat: torch.Tensor, + return_dict: bool = True, + ) -> Union[KarrasVeOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + sigma_hat (`float`): + sigma_prev (`float`): + sample_hat (`torch.Tensor`): + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_karras_ve.KarrasVESchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_karras_ve.KarrasVESchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_karras_ve.KarrasVESchedulerOutput`] is returned, + otherwise a tuple is returned where the first element is the sample tensor. + + """ + + pred_original_sample = sample_hat + sigma_hat * model_output + derivative = (sample_hat - pred_original_sample) / sigma_hat + sample_prev = sample_hat + (sigma_prev - sigma_hat) * derivative + + if not return_dict: + return (sample_prev, derivative) + + return KarrasVeOutput( + prev_sample=sample_prev, derivative=derivative, pred_original_sample=pred_original_sample + ) + + def step_correct( + self, + model_output: torch.Tensor, + sigma_hat: float, + sigma_prev: float, + sample_hat: torch.Tensor, + sample_prev: torch.Tensor, + derivative: torch.Tensor, + return_dict: bool = True, + ) -> Union[KarrasVeOutput, Tuple]: + """ + Corrects the predicted sample based on the `model_output` of the network. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + sigma_hat (`float`): TODO + sigma_prev (`float`): TODO + sample_hat (`torch.Tensor`): TODO + sample_prev (`torch.Tensor`): TODO + derivative (`torch.Tensor`): TODO + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_ddpm.DDPMSchedulerOutput`] or `tuple`. + + Returns: + prev_sample (TODO): updated sample in the diffusion chain. derivative (TODO): TODO + + """ + pred_original_sample = sample_prev + sigma_prev * model_output + derivative_corr = (sample_prev - pred_original_sample) / sigma_prev + sample_prev = sample_hat + (sigma_prev - sigma_hat) * (0.5 * derivative + 0.5 * derivative_corr) + + if not return_dict: + return (sample_prev, derivative) + + return KarrasVeOutput( + prev_sample=sample_prev, derivative=derivative, pred_original_sample=pred_original_sample + ) + + def add_noise(self, original_samples, noise, timesteps): + raise NotImplementedError() diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/deprecated/scheduling_sde_vp.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/deprecated/scheduling_sde_vp.py new file mode 100644 index 0000000000000000000000000000000000000000..09b02cadc4008b1d80184a355a06201a85f97e8f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/deprecated/scheduling_sde_vp.py @@ -0,0 +1,109 @@ +# Copyright 2024 Google Brain and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/yang-song/score_sde_pytorch + +import math +from typing import Union + +import torch + +from ...configuration_utils import ConfigMixin, register_to_config +from ...utils.torch_utils import randn_tensor +from ..scheduling_utils import SchedulerMixin + + +class ScoreSdeVpScheduler(SchedulerMixin, ConfigMixin): + """ + `ScoreSdeVpScheduler` is a variance preserving stochastic differential equation (SDE) scheduler. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 2000): + The number of diffusion steps to train the model. + beta_min (`int`, defaults to 0.1): + beta_max (`int`, defaults to 20): + sampling_eps (`int`, defaults to 1e-3): + The end value of sampling where timesteps decrease progressively from 1 to epsilon. + """ + + order = 1 + + @register_to_config + def __init__(self, num_train_timesteps=2000, beta_min=0.1, beta_max=20, sampling_eps=1e-3): + self.sigmas = None + self.discrete_sigmas = None + self.timesteps = None + + def set_timesteps(self, num_inference_steps, device: Union[str, torch.device] = None): + """ + Sets the continuous timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + self.timesteps = torch.linspace(1, self.config.sampling_eps, num_inference_steps, device=device) + + def step_pred(self, score, x, t, generator=None): + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + score (): + x (): + t (): + generator (`torch.Generator`, *optional*): + A random number generator. + """ + if self.timesteps is None: + raise ValueError( + "`self.timesteps` is not set, you need to run 'set_timesteps' after creating the scheduler" + ) + + # TODO(Patrick) better comments + non-PyTorch + # postprocess model score + log_mean_coeff = -0.25 * t**2 * (self.config.beta_max - self.config.beta_min) - 0.5 * t * self.config.beta_min + std = torch.sqrt(1.0 - torch.exp(2.0 * log_mean_coeff)) + std = std.flatten() + while len(std.shape) < len(score.shape): + std = std.unsqueeze(-1) + score = -score / std + + # compute + dt = -1.0 / len(self.timesteps) + + beta_t = self.config.beta_min + t * (self.config.beta_max - self.config.beta_min) + beta_t = beta_t.flatten() + while len(beta_t.shape) < len(x.shape): + beta_t = beta_t.unsqueeze(-1) + drift = -0.5 * beta_t * x + + diffusion = torch.sqrt(beta_t) + drift = drift - diffusion**2 * score + x_mean = x + drift * dt + + # add noise + noise = randn_tensor(x.shape, layout=x.layout, generator=generator, device=x.device, dtype=x.dtype) + x = x_mean + diffusion * math.sqrt(-dt) * noise + + return x, x_mean + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_amused.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_amused.py new file mode 100644 index 0000000000000000000000000000000000000000..238b8d8691715a83105df815c0ebcad748092ec1 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_amused.py @@ -0,0 +1,162 @@ +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from .scheduling_utils import SchedulerMixin + + +def gumbel_noise(t, generator=None): + device = generator.device if generator is not None else t.device + noise = torch.zeros_like(t, device=device).uniform_(0, 1, generator=generator).to(t.device) + return -torch.log((-torch.log(noise.clamp(1e-20))).clamp(1e-20)) + + +def mask_by_random_topk(mask_len, probs, temperature=1.0, generator=None): + confidence = torch.log(probs.clamp(1e-20)) + temperature * gumbel_noise(probs, generator=generator) + sorted_confidence = torch.sort(confidence, dim=-1).values + cut_off = torch.gather(sorted_confidence, 1, mask_len.long()) + masking = confidence < cut_off + return masking + + +@dataclass +class AmusedSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: torch.Tensor = None + + +class AmusedScheduler(SchedulerMixin, ConfigMixin): + order = 1 + + temperatures: torch.Tensor + + @register_to_config + def __init__( + self, + mask_token_id: int, + masking_schedule: str = "cosine", + ): + self.temperatures = None + self.timesteps = None + + def set_timesteps( + self, + num_inference_steps: int, + temperature: Union[int, Tuple[int, int], List[int]] = (2, 0), + device: Union[str, torch.device] = None, + ): + self.timesteps = torch.arange(num_inference_steps, device=device).flip(0) + + if isinstance(temperature, (tuple, list)): + self.temperatures = torch.linspace(temperature[0], temperature[1], num_inference_steps, device=device) + else: + self.temperatures = torch.linspace(temperature, 0.01, num_inference_steps, device=device) + + def step( + self, + model_output: torch.Tensor, + timestep: torch.long, + sample: torch.LongTensor, + starting_mask_ratio: int = 1, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[AmusedSchedulerOutput, Tuple]: + two_dim_input = sample.ndim == 3 and model_output.ndim == 4 + + if two_dim_input: + batch_size, codebook_size, height, width = model_output.shape + sample = sample.reshape(batch_size, height * width) + model_output = model_output.reshape(batch_size, codebook_size, height * width).permute(0, 2, 1) + + unknown_map = sample == self.config.mask_token_id + + probs = model_output.softmax(dim=-1) + + device = probs.device + probs_ = probs.to(generator.device) if generator is not None else probs # handles when generator is on CPU + if probs_.device.type == "cpu" and probs_.dtype != torch.float32: + probs_ = probs_.float() # multinomial is not implemented for cpu half precision + probs_ = probs_.reshape(-1, probs.size(-1)) + pred_original_sample = torch.multinomial(probs_, 1, generator=generator).to(device=device) + pred_original_sample = pred_original_sample[:, 0].view(*probs.shape[:-1]) + pred_original_sample = torch.where(unknown_map, pred_original_sample, sample) + + if timestep == 0: + prev_sample = pred_original_sample + else: + seq_len = sample.shape[1] + step_idx = (self.timesteps == timestep).nonzero() + ratio = (step_idx + 1) / len(self.timesteps) + + if self.config.masking_schedule == "cosine": + mask_ratio = torch.cos(ratio * math.pi / 2) + elif self.config.masking_schedule == "linear": + mask_ratio = 1 - ratio + else: + raise ValueError(f"unknown masking schedule {self.config.masking_schedule}") + + mask_ratio = starting_mask_ratio * mask_ratio + + mask_len = (seq_len * mask_ratio).floor() + # do not mask more than amount previously masked + mask_len = torch.min(unknown_map.sum(dim=-1, keepdim=True) - 1, mask_len) + # mask at least one + mask_len = torch.max(torch.tensor([1], device=model_output.device), mask_len) + + selected_probs = torch.gather(probs, -1, pred_original_sample[:, :, None])[:, :, 0] + # Ignores the tokens given in the input by overwriting their confidence. + selected_probs = torch.where(unknown_map, selected_probs, torch.finfo(selected_probs.dtype).max) + + masking = mask_by_random_topk(mask_len, selected_probs, self.temperatures[step_idx], generator) + + # Masks tokens with lower confidence. + prev_sample = torch.where(masking, self.config.mask_token_id, pred_original_sample) + + if two_dim_input: + prev_sample = prev_sample.reshape(batch_size, height, width) + pred_original_sample = pred_original_sample.reshape(batch_size, height, width) + + if not return_dict: + return (prev_sample, pred_original_sample) + + return AmusedSchedulerOutput(prev_sample, pred_original_sample) + + def add_noise(self, sample, timesteps, generator=None): + step_idx = (self.timesteps == timesteps).nonzero() + ratio = (step_idx + 1) / len(self.timesteps) + + if self.config.masking_schedule == "cosine": + mask_ratio = torch.cos(ratio * math.pi / 2) + elif self.config.masking_schedule == "linear": + mask_ratio = 1 - ratio + else: + raise ValueError(f"unknown masking schedule {self.config.masking_schedule}") + + mask_indices = ( + torch.rand( + sample.shape, device=generator.device if generator is not None else sample.device, generator=generator + ).to(sample.device) + < mask_ratio + ) + + masked_sample = sample.clone() + + masked_sample[mask_indices] = self.config.mask_token_id + + return masked_sample diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_consistency_decoder.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_consistency_decoder.py new file mode 100644 index 0000000000000000000000000000000000000000..d7af018b284a59878c3cae86cec57e02d344e227 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_consistency_decoder.py @@ -0,0 +1,180 @@ +import math +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import SchedulerMixin + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +@dataclass +class ConsistencyDecoderSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + """ + + prev_sample: torch.Tensor + + +class ConsistencyDecoderScheduler(SchedulerMixin, ConfigMixin): + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1024, + sigma_data: float = 0.5, + ): + betas = betas_for_alpha_bar(num_train_timesteps) + + alphas = 1.0 - betas + alphas_cumprod = torch.cumprod(alphas, dim=0) + + self.sqrt_alphas_cumprod = torch.sqrt(alphas_cumprod) + self.sqrt_one_minus_alphas_cumprod = torch.sqrt(1.0 - alphas_cumprod) + + sigmas = torch.sqrt(1.0 / alphas_cumprod - 1) + + sqrt_recip_alphas_cumprod = torch.sqrt(1.0 / alphas_cumprod) + + self.c_skip = sqrt_recip_alphas_cumprod * sigma_data**2 / (sigmas**2 + sigma_data**2) + self.c_out = sigmas * sigma_data / (sigmas**2 + sigma_data**2) ** 0.5 + self.c_in = sqrt_recip_alphas_cumprod / (sigmas**2 + sigma_data**2) ** 0.5 + + def set_timesteps( + self, + num_inference_steps: Optional[int] = None, + device: Union[str, torch.device] = None, + ): + if num_inference_steps != 2: + raise ValueError("Currently more than 2 inference steps are not supported.") + + self.timesteps = torch.tensor([1008, 512], dtype=torch.long, device=device) + self.sqrt_alphas_cumprod = self.sqrt_alphas_cumprod.to(device) + self.sqrt_one_minus_alphas_cumprod = self.sqrt_one_minus_alphas_cumprod.to(device) + self.c_skip = self.c_skip.to(device) + self.c_out = self.c_out.to(device) + self.c_in = self.c_in.to(device) + + @property + def init_noise_sigma(self): + return self.sqrt_one_minus_alphas_cumprod[self.timesteps[0]] + + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample * self.c_in[timestep] + + def step( + self, + model_output: torch.Tensor, + timestep: Union[float, torch.Tensor], + sample: torch.Tensor, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[ConsistencyDecoderSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + timestep (`float`): + The current timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a + [`~schedulers.scheduling_consistency_models.ConsistencyDecoderSchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_consistency_models.ConsistencyDecoderSchedulerOutput`] or `tuple`: + If return_dict is `True`, + [`~schedulers.scheduling_consistency_models.ConsistencyDecoderSchedulerOutput`] is returned, otherwise + a tuple is returned where the first element is the sample tensor. + """ + x_0 = self.c_out[timestep] * model_output + self.c_skip[timestep] * sample + + timestep_idx = torch.where(self.timesteps == timestep)[0] + + if timestep_idx == len(self.timesteps) - 1: + prev_sample = x_0 + else: + noise = randn_tensor(x_0.shape, generator=generator, dtype=x_0.dtype, device=x_0.device) + prev_sample = ( + self.sqrt_alphas_cumprod[self.timesteps[timestep_idx + 1]].to(x_0.dtype) * x_0 + + self.sqrt_one_minus_alphas_cumprod[self.timesteps[timestep_idx + 1]].to(x_0.dtype) * noise + ) + + if not return_dict: + return (prev_sample,) + + return ConsistencyDecoderSchedulerOutput(prev_sample=prev_sample) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_consistency_models.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_consistency_models.py new file mode 100644 index 0000000000000000000000000000000000000000..c946fa1681c0ae5257070ffc9d51768a60e61f73 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_consistency_models.py @@ -0,0 +1,445 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput, logging +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import SchedulerMixin + + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + + +@dataclass +class CMStochasticIterativeSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + """ + + prev_sample: torch.Tensor + + +class CMStochasticIterativeScheduler(SchedulerMixin, ConfigMixin): + """ + Multistep and onestep sampling for consistency models. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 40): + The number of diffusion steps to train the model. + sigma_min (`float`, defaults to 0.002): + Minimum noise magnitude in the sigma schedule. Defaults to 0.002 from the original implementation. + sigma_max (`float`, defaults to 80.0): + Maximum noise magnitude in the sigma schedule. Defaults to 80.0 from the original implementation. + sigma_data (`float`, defaults to 0.5): + The standard deviation of the data distribution from the EDM + [paper](https://huggingface.co/papers/2206.00364). Defaults to 0.5 from the original implementation. + s_noise (`float`, defaults to 1.0): + The amount of additional noise to counteract loss of detail during sampling. A reasonable range is [1.000, + 1.011]. Defaults to 1.0 from the original implementation. + rho (`float`, defaults to 7.0): + The parameter for calculating the Karras sigma schedule from the EDM + [paper](https://huggingface.co/papers/2206.00364). Defaults to 7.0 from the original implementation. + clip_denoised (`bool`, defaults to `True`): + Whether to clip the denoised outputs to `(-1, 1)`. + timesteps (`List` or `np.ndarray` or `torch.Tensor`, *optional*): + An explicit timestep schedule that can be optionally specified. The timesteps are expected to be in + increasing order. + """ + + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 40, + sigma_min: float = 0.002, + sigma_max: float = 80.0, + sigma_data: float = 0.5, + s_noise: float = 1.0, + rho: float = 7.0, + clip_denoised: bool = True, + ): + # standard deviation of the initial noise distribution + self.init_noise_sigma = sigma_max + + ramp = np.linspace(0, 1, num_train_timesteps) + sigmas = self._convert_to_karras(ramp) + timesteps = self.sigma_to_t(sigmas) + + # setable values + self.num_inference_steps = None + self.sigmas = torch.from_numpy(sigmas) + self.timesteps = torch.from_numpy(timesteps) + self.custom_timesteps = False + self.is_scale_input_called = False + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def scale_model_input(self, sample: torch.Tensor, timestep: Union[float, torch.Tensor]) -> torch.Tensor: + """ + Scales the consistency model input by `(sigma**2 + sigma_data**2) ** 0.5`. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`float` or `torch.Tensor`): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + # Get sigma corresponding to timestep + if self.step_index is None: + self._init_step_index(timestep) + + sigma = self.sigmas[self.step_index] + + sample = sample / ((sigma**2 + self.config.sigma_data**2) ** 0.5) + + self.is_scale_input_called = True + return sample + + def sigma_to_t(self, sigmas: Union[float, np.ndarray]): + """ + Gets scaled timesteps from the Karras sigmas for input to the consistency model. + + Args: + sigmas (`float` or `np.ndarray`): + A single Karras sigma or an array of Karras sigmas. + + Returns: + `float` or `np.ndarray`: + A scaled input timestep or scaled input timestep array. + """ + if not isinstance(sigmas, np.ndarray): + sigmas = np.array(sigmas, dtype=np.float64) + + timesteps = 1000 * 0.25 * np.log(sigmas + 1e-44) + + return timesteps + + def set_timesteps( + self, + num_inference_steps: Optional[int] = None, + device: Union[str, torch.device] = None, + timesteps: Optional[List[int]] = None, + ): + """ + Sets the timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + timesteps (`List[int]`, *optional*): + Custom timesteps used to support arbitrary spacing between timesteps. If `None`, then the default + timestep spacing strategy of equal spacing between timesteps is used. If `timesteps` is passed, + `num_inference_steps` must be `None`. + """ + if num_inference_steps is None and timesteps is None: + raise ValueError("Exactly one of `num_inference_steps` or `timesteps` must be supplied.") + + if num_inference_steps is not None and timesteps is not None: + raise ValueError("Can only pass one of `num_inference_steps` or `timesteps`.") + + # Follow DDPMScheduler custom timesteps logic + if timesteps is not None: + for i in range(1, len(timesteps)): + if timesteps[i] >= timesteps[i - 1]: + raise ValueError("`timesteps` must be in descending order.") + + if timesteps[0] >= self.config.num_train_timesteps: + raise ValueError( + f"`timesteps` must start before `self.config.train_timesteps`: {self.config.num_train_timesteps}." + ) + + timesteps = np.array(timesteps, dtype=np.int64) + self.custom_timesteps = True + else: + if num_inference_steps > self.config.num_train_timesteps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `self.config.train_timesteps`:" + f" {self.config.num_train_timesteps} as the unet model trained with this scheduler can only handle" + f" maximal {self.config.num_train_timesteps} timesteps." + ) + + self.num_inference_steps = num_inference_steps + + step_ratio = self.config.num_train_timesteps // self.num_inference_steps + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.int64) + self.custom_timesteps = False + + # Map timesteps to Karras sigmas directly for multistep sampling + # See https://github.com/openai/consistency_models/blob/main/cm/karras_diffusion.py#L675 + num_train_timesteps = self.config.num_train_timesteps + ramp = timesteps[::-1].copy() + ramp = ramp / (num_train_timesteps - 1) + sigmas = self._convert_to_karras(ramp) + timesteps = self.sigma_to_t(sigmas) + + sigmas = np.concatenate([sigmas, [self.config.sigma_min]]).astype(np.float32) + self.sigmas = torch.from_numpy(sigmas).to(device=device) + + if str(device).startswith("mps"): + # mps does not support float64 + self.timesteps = torch.from_numpy(timesteps).to(device, dtype=torch.float32) + else: + self.timesteps = torch.from_numpy(timesteps).to(device=device) + + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Modified _convert_to_karras implementation that takes in ramp as argument + def _convert_to_karras(self, ramp): + """Constructs the noise schedule of Karras et al. (2022).""" + + sigma_min: float = self.config.sigma_min + sigma_max: float = self.config.sigma_max + + rho = self.config.rho + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + def get_scalings(self, sigma): + sigma_data = self.config.sigma_data + + c_skip = sigma_data**2 / (sigma**2 + sigma_data**2) + c_out = sigma * sigma_data / (sigma**2 + sigma_data**2) ** 0.5 + return c_skip, c_out + + def get_scalings_for_boundary_condition(self, sigma): + """ + Gets the scalings used in the consistency model parameterization (from Appendix C of the + [paper](https://huggingface.co/papers/2303.01469)) to enforce boundary condition. + + + + `epsilon` in the equations for `c_skip` and `c_out` is set to `sigma_min`. + + + + Args: + sigma (`torch.Tensor`): + The current sigma in the Karras sigma schedule. + + Returns: + `tuple`: + A two-element tuple where `c_skip` (which weights the current sample) is the first element and `c_out` + (which weights the consistency model output) is the second element. + """ + sigma_min = self.config.sigma_min + sigma_data = self.config.sigma_data + + c_skip = sigma_data**2 / ((sigma - sigma_min) ** 2 + sigma_data**2) + c_out = (sigma - sigma_min) * sigma_data / (sigma**2 + sigma_data**2) ** 0.5 + return c_skip, c_out + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._init_step_index + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.Tensor, + timestep: Union[float, torch.Tensor], + sample: torch.Tensor, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[CMStochasticIterativeSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + timestep (`float`): + The current timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a + [`~schedulers.scheduling_consistency_models.CMStochasticIterativeSchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_consistency_models.CMStochasticIterativeSchedulerOutput`] or `tuple`: + If return_dict is `True`, + [`~schedulers.scheduling_consistency_models.CMStochasticIterativeSchedulerOutput`] is returned, + otherwise a tuple is returned where the first element is the sample tensor. + """ + + if isinstance(timestep, (int, torch.IntTensor, torch.LongTensor)): + raise ValueError( + ( + "Passing integer indices (e.g. from `enumerate(timesteps)`) as timesteps to" + f" `{self.__class__}.step()` is not supported. Make sure to pass" + " one of the `scheduler.timesteps` as a timestep." + ), + ) + + if not self.is_scale_input_called: + logger.warning( + "The `scale_model_input` function should be called before `step` to ensure correct denoising. " + "See `StableDiffusionPipeline` for a usage example." + ) + + sigma_min = self.config.sigma_min + sigma_max = self.config.sigma_max + + if self.step_index is None: + self._init_step_index(timestep) + + # sigma_next corresponds to next_t in original implementation + sigma = self.sigmas[self.step_index] + if self.step_index + 1 < self.config.num_train_timesteps: + sigma_next = self.sigmas[self.step_index + 1] + else: + # Set sigma_next to sigma_min + sigma_next = self.sigmas[-1] + + # Get scalings for boundary conditions + c_skip, c_out = self.get_scalings_for_boundary_condition(sigma) + + # 1. Denoise model output using boundary conditions + denoised = c_out * model_output + c_skip * sample + if self.config.clip_denoised: + denoised = denoised.clamp(-1, 1) + + # 2. Sample z ~ N(0, s_noise^2 * I) + # Noise is not used for onestep sampling. + if len(self.timesteps) > 1: + noise = randn_tensor( + model_output.shape, dtype=model_output.dtype, device=model_output.device, generator=generator + ) + else: + noise = torch.zeros_like(model_output) + z = noise * self.config.s_noise + + sigma_hat = sigma_next.clamp(min=sigma_min, max=sigma_max) + + # 3. Return noisy sample + # tau = sigma_hat, eps = sigma_min + prev_sample = denoised + z * (sigma_hat**2 - sigma_min**2) ** 0.5 + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return (prev_sample,) + + return CMStochasticIterativeSchedulerOutput(prev_sample=prev_sample) + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.Tensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # self.begin_index is None when scheduler is used for training, or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + noisy_samples = original_samples + noise * sigma + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_cosine_dpmsolver_multistep.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_cosine_dpmsolver_multistep.py new file mode 100644 index 0000000000000000000000000000000000000000..0eca18f044e91878ee2b3f6028de36c99142bf9a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_cosine_dpmsolver_multistep.py @@ -0,0 +1,577 @@ +# Copyright 2024 TSAIL Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/LuChengTHU/dpm-solver and https://github.com/NVlabs/edm + +import math +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from .scheduling_dpmsolver_sde import BrownianTreeNoiseSampler +from .scheduling_utils import SchedulerMixin, SchedulerOutput + + +class CosineDPMSolverMultistepScheduler(SchedulerMixin, ConfigMixin): + """ + Implements a variant of `DPMSolverMultistepScheduler` with cosine schedule, proposed by Nichol and Dhariwal (2021). + This scheduler was used in Stable Audio Open [1]. + + [1] Evans, Parker, et al. "Stable Audio Open" https://huggingface.co/papers/2407.14358 + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + sigma_min (`float`, *optional*, defaults to 0.3): + Minimum noise magnitude in the sigma schedule. This was set to 0.3 in Stable Audio Open [1]. + sigma_max (`float`, *optional*, defaults to 500): + Maximum noise magnitude in the sigma schedule. This was set to 500 in Stable Audio Open [1]. + sigma_data (`float`, *optional*, defaults to 1.0): + The standard deviation of the data distribution. This is set to 1.0 in Stable Audio Open [1]. + sigma_schedule (`str`, *optional*, defaults to `exponential`): + Sigma schedule to compute the `sigmas`. By default, we the schedule introduced in the EDM paper + (https://huggingface.co/papers/2206.00364). Other acceptable value is "exponential". The exponential + schedule was incorporated in this model: https://huggingface.co/stabilityai/cosxl. + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + solver_order (`int`, defaults to 2): + The DPMSolver order which can be `1` or `2`. It is recommended to use `solver_order=2`. + prediction_type (`str`, defaults to `v_prediction`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + solver_type (`str`, defaults to `midpoint`): + Solver type for the second-order solver; can be `midpoint` or `heun`. The solver type slightly affects the + sample quality, especially for a small number of steps. It is recommended to use `midpoint` solvers. + lower_order_final (`bool`, defaults to `True`): + Whether to use lower-order solvers in the final steps. Only valid for < 15 inference steps. This can + stabilize the sampling of DPMSolver for steps < 15, especially for steps <= 10. + euler_at_final (`bool`, defaults to `False`): + Whether to use Euler's method in the final step. It is a trade-off between numerical stability and detail + richness. This can stabilize the sampling of the SDE variant of DPMSolver for small number of inference + steps, but sometimes may result in blurring. + final_sigmas_type (`str`, defaults to `"zero"`): + The final `sigma` value for the noise schedule during the sampling process. If `"sigma_min"`, the final + sigma is the same as the last sigma in the training schedule. If `zero`, the final sigma is set to 0. + """ + + _compatibles = [] + order = 1 + + @register_to_config + def __init__( + self, + sigma_min: float = 0.3, + sigma_max: float = 500, + sigma_data: float = 1.0, + sigma_schedule: str = "exponential", + num_train_timesteps: int = 1000, + solver_order: int = 2, + prediction_type: str = "v_prediction", + rho: float = 7.0, + solver_type: str = "midpoint", + lower_order_final: bool = True, + euler_at_final: bool = False, + final_sigmas_type: Optional[str] = "zero", # "zero", "sigma_min" + ): + if solver_type not in ["midpoint", "heun"]: + if solver_type in ["logrho", "bh1", "bh2"]: + self.register_to_config(solver_type="midpoint") + else: + raise NotImplementedError(f"{solver_type} is not implemented for {self.__class__}") + + ramp = torch.linspace(0, 1, num_train_timesteps) + if sigma_schedule == "karras": + sigmas = self._compute_karras_sigmas(ramp) + elif sigma_schedule == "exponential": + sigmas = self._compute_exponential_sigmas(ramp) + + self.timesteps = self.precondition_noise(sigmas) + + self.sigmas = torch.cat([sigmas, torch.zeros(1, device=sigmas.device)]) + + # setable values + self.num_inference_steps = None + self.model_outputs = [None] * solver_order + self.lower_order_nums = 0 + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def init_noise_sigma(self): + # standard deviation of the initial noise distribution + return (self.config.sigma_max**2 + 1) ** 0.5 + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + # Copied from diffusers.schedulers.scheduling_edm_euler.EDMEulerScheduler.precondition_inputs + def precondition_inputs(self, sample, sigma): + c_in = self._get_conditioning_c_in(sigma) + scaled_sample = sample * c_in + return scaled_sample + + def precondition_noise(self, sigma): + if not isinstance(sigma, torch.Tensor): + sigma = torch.tensor([sigma]) + + return sigma.atan() / math.pi * 2 + + # Copied from diffusers.schedulers.scheduling_edm_euler.EDMEulerScheduler.precondition_outputs + def precondition_outputs(self, sample, model_output, sigma): + sigma_data = self.config.sigma_data + c_skip = sigma_data**2 / (sigma**2 + sigma_data**2) + + if self.config.prediction_type == "epsilon": + c_out = sigma * sigma_data / (sigma**2 + sigma_data**2) ** 0.5 + elif self.config.prediction_type == "v_prediction": + c_out = -sigma * sigma_data / (sigma**2 + sigma_data**2) ** 0.5 + else: + raise ValueError(f"Prediction type {self.config.prediction_type} is not supported.") + + denoised = c_skip * sample + c_out * model_output + + return denoised + + # Copied from diffusers.schedulers.scheduling_edm_euler.EDMEulerScheduler.scale_model_input + def scale_model_input(self, sample: torch.Tensor, timestep: Union[float, torch.Tensor]) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. Scales the denoising model input by `(sigma**2 + 1) ** 0.5` to match the Euler algorithm. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + if self.step_index is None: + self._init_step_index(timestep) + + sigma = self.sigmas[self.step_index] + sample = self.precondition_inputs(sample, sigma) + + self.is_scale_input_called = True + return sample + + def set_timesteps(self, num_inference_steps: int = None, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + + self.num_inference_steps = num_inference_steps + + ramp = torch.linspace(0, 1, self.num_inference_steps) + if self.config.sigma_schedule == "karras": + sigmas = self._compute_karras_sigmas(ramp) + elif self.config.sigma_schedule == "exponential": + sigmas = self._compute_exponential_sigmas(ramp) + + sigmas = sigmas.to(dtype=torch.float32, device=device) + self.timesteps = self.precondition_noise(sigmas) + + if self.config.final_sigmas_type == "sigma_min": + sigma_last = self.config.sigma_min + elif self.config.final_sigmas_type == "zero": + sigma_last = 0 + else: + raise ValueError( + f"`final_sigmas_type` must be one of 'zero', or 'sigma_min', but got {self.config.final_sigmas_type}" + ) + + self.sigmas = torch.cat([sigmas, torch.tensor([sigma_last], dtype=torch.float32, device=device)]) + + self.model_outputs = [ + None, + ] * self.config.solver_order + self.lower_order_nums = 0 + + # add an index counter for schedulers that allow duplicated timesteps + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # if a noise sampler is used, reinitialise it + self.noise_sampler = None + + # Copied from diffusers.schedulers.scheduling_edm_euler.EDMEulerScheduler._compute_karras_sigmas + def _compute_karras_sigmas(self, ramp, sigma_min=None, sigma_max=None) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + sigma_min = sigma_min or self.config.sigma_min + sigma_max = sigma_max or self.config.sigma_max + + rho = self.config.rho + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_edm_euler.EDMEulerScheduler._compute_exponential_sigmas + def _compute_exponential_sigmas(self, ramp, sigma_min=None, sigma_max=None) -> torch.Tensor: + """Implementation closely follows k-diffusion. + + https://github.com/crowsonkb/k-diffusion/blob/6ab5146d4a5ef63901326489f31f1d8e7dd36b48/k_diffusion/sampling.py#L26 + """ + sigma_min = sigma_min or self.config.sigma_min + sigma_max = sigma_max or self.config.sigma_max + sigmas = torch.linspace(math.log(sigma_min), math.log(sigma_max), len(ramp)).exp().flip(0) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._sigma_to_t + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + def _sigma_to_alpha_sigma_t(self, sigma): + alpha_t = torch.tensor(1) # Inputs are pre-scaled before going into unet, so alpha_t = 1 + sigma_t = sigma + + return alpha_t, sigma_t + + def convert_model_output( + self, + model_output: torch.Tensor, + sample: torch.Tensor = None, + ) -> torch.Tensor: + """ + Convert the model output to the corresponding type the DPMSolver/DPMSolver++ algorithm needs. DPM-Solver is + designed to discretize an integral of the noise prediction model, and DPM-Solver++ is designed to discretize an + integral of the data prediction model. + + + + The algorithm and model type are decoupled. You can use either DPMSolver or DPMSolver++ for both noise + prediction and data prediction models. + + + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The converted model output. + """ + sigma = self.sigmas[self.step_index] + x0_pred = self.precondition_outputs(sample, model_output, sigma) + + return x0_pred + + def dpm_solver_first_order_update( + self, + model_output: torch.Tensor, + sample: torch.Tensor = None, + noise: Optional[torch.Tensor] = None, + ) -> torch.Tensor: + """ + One step for the first-order DPMSolver (equivalent to DDIM). + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + sigma_t, sigma_s = self.sigmas[self.step_index + 1], self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s, sigma_s = self._sigma_to_alpha_sigma_t(sigma_s) + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s = torch.log(alpha_s) - torch.log(sigma_s) + + h = lambda_t - lambda_s + assert noise is not None + x_t = ( + (sigma_t / sigma_s * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * model_output + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + + return x_t + + def multistep_dpm_solver_second_order_update( + self, + model_output_list: List[torch.Tensor], + sample: torch.Tensor = None, + noise: Optional[torch.Tensor] = None, + ) -> torch.Tensor: + """ + One step for the second-order multistep DPMSolver. + + Args: + model_output_list (`List[torch.Tensor]`): + The direct outputs from learned diffusion model at current and latter timesteps. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + sigma_t, sigma_s0, sigma_s1 = ( + self.sigmas[self.step_index + 1], + self.sigmas[self.step_index], + self.sigmas[self.step_index - 1], + ) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + alpha_s1, sigma_s1 = self._sigma_to_alpha_sigma_t(sigma_s1) + + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s0 = torch.log(alpha_s0) - torch.log(sigma_s0) + lambda_s1 = torch.log(alpha_s1) - torch.log(sigma_s1) + + m0, m1 = model_output_list[-1], model_output_list[-2] + + h, h_0 = lambda_t - lambda_s0, lambda_s0 - lambda_s1 + r0 = h_0 / h + D0, D1 = m0, (1.0 / r0) * (m0 - m1) + + # sde-dpmsolver++ + assert noise is not None + if self.config.solver_type == "midpoint": + x_t = ( + (sigma_t / sigma_s0 * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * D0 + + 0.5 * (alpha_t * (1 - torch.exp(-2.0 * h))) * D1 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + elif self.config.solver_type == "heun": + x_t = ( + (sigma_t / sigma_s0 * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * D0 + + (alpha_t * ((1.0 - torch.exp(-2.0 * h)) / (-2.0 * h) + 1.0)) * D1 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + + return x_t + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + index_candidates = (schedule_timesteps == timestep).nonzero() + + if len(index_candidates) == 0: + step_index = len(self.timesteps) - 1 + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + elif len(index_candidates) > 1: + step_index = index_candidates[1].item() + else: + step_index = index_candidates[0].item() + + return step_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler._init_step_index + def _init_step_index(self, timestep): + """ + Initialize the step_index counter for the scheduler. + """ + + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.Tensor, + timestep: Union[int, torch.Tensor], + sample: torch.Tensor, + generator=None, + return_dict: bool = True, + ) -> Union[SchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the sample with + the multistep DPMSolver. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_utils.SchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + if self.step_index is None: + self._init_step_index(timestep) + + # Improve numerical stability for small number of steps + lower_order_final = (self.step_index == len(self.timesteps) - 1) and ( + self.config.euler_at_final + or (self.config.lower_order_final and len(self.timesteps) < 15) + or self.config.final_sigmas_type == "zero" + ) + lower_order_second = ( + (self.step_index == len(self.timesteps) - 2) and self.config.lower_order_final and len(self.timesteps) < 15 + ) + + model_output = self.convert_model_output(model_output, sample=sample) + for i in range(self.config.solver_order - 1): + self.model_outputs[i] = self.model_outputs[i + 1] + self.model_outputs[-1] = model_output + + if self.noise_sampler is None: + seed = None + if generator is not None: + seed = ( + [g.initial_seed() for g in generator] if isinstance(generator, list) else generator.initial_seed() + ) + self.noise_sampler = BrownianTreeNoiseSampler( + model_output, sigma_min=self.config.sigma_min, sigma_max=self.config.sigma_max, seed=seed + ) + noise = self.noise_sampler(self.sigmas[self.step_index], self.sigmas[self.step_index + 1]).to( + model_output.device + ) + + if self.config.solver_order == 1 or self.lower_order_nums < 1 or lower_order_final: + prev_sample = self.dpm_solver_first_order_update(model_output, sample=sample, noise=noise) + elif self.config.solver_order == 2 or self.lower_order_nums < 2 or lower_order_second: + prev_sample = self.multistep_dpm_solver_second_order_update(self.model_outputs, sample=sample, noise=noise) + + if self.lower_order_nums < self.config.solver_order: + self.lower_order_nums += 1 + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return (prev_sample,) + + return SchedulerOutput(prev_sample=prev_sample) + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.Tensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # self.begin_index is None when scheduler is used for training, or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + noisy_samples = original_samples + noise * sigma + return noisy_samples + + # Copied from diffusers.schedulers.scheduling_edm_euler.EDMEulerScheduler._get_conditioning_c_in + def _get_conditioning_c_in(self, sigma): + c_in = 1 / ((sigma**2 + self.config.sigma_data**2) ** 0.5) + return c_in + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim.py new file mode 100644 index 0000000000000000000000000000000000000000..6d7ff396ce0c4490a268d932a149ef853ef75afb --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim.py @@ -0,0 +1,521 @@ +# Copyright 2024 Stanford University Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This code is strongly influenced by https://github.com/pesser/pytorch_diffusion +# and https://github.com/hojonathanho/diffusion + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->DDIM +class DDIMSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +def rescale_zero_terminal_snr(betas): + """ + Rescales betas to have zero terminal SNR Based on https://huggingface.co/papers/2305.08891 (Algorithm 1) + + + Args: + betas (`torch.Tensor`): + the betas that the scheduler is being initialized with. + + Returns: + `torch.Tensor`: rescaled betas with zero terminal SNR + """ + # Convert betas to alphas_bar_sqrt + alphas = 1.0 - betas + alphas_cumprod = torch.cumprod(alphas, dim=0) + alphas_bar_sqrt = alphas_cumprod.sqrt() + + # Store old values. + alphas_bar_sqrt_0 = alphas_bar_sqrt[0].clone() + alphas_bar_sqrt_T = alphas_bar_sqrt[-1].clone() + + # Shift so the last timestep is zero. + alphas_bar_sqrt -= alphas_bar_sqrt_T + + # Scale so the first timestep is back to the old value. + alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T) + + # Convert alphas_bar_sqrt to betas + alphas_bar = alphas_bar_sqrt**2 # Revert sqrt + alphas = alphas_bar[1:] / alphas_bar[:-1] # Revert cumprod + alphas = torch.cat([alphas_bar[0:1], alphas]) + betas = 1 - alphas + + return betas + + +class DDIMScheduler(SchedulerMixin, ConfigMixin): + """ + `DDIMScheduler` extends the denoising procedure introduced in denoising diffusion probabilistic models (DDPMs) with + non-Markovian guidance. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + clip_sample (`bool`, defaults to `True`): + Clip the predicted sample for numerical stability. + clip_sample_range (`float`, defaults to 1.0): + The maximum magnitude for sample clipping. Valid only when `clip_sample=True`. + set_alpha_to_one (`bool`, defaults to `True`): + Each diffusion step uses the alphas product value at that step and at the previous one. For the final step + there is no previous alpha. When this option is `True` the previous alpha product is fixed to `1`, + otherwise it uses the alpha value at step 0. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + thresholding (`bool`, defaults to `False`): + Whether to use the "dynamic thresholding" method. This is unsuitable for latent-space diffusion models such + as Stable Diffusion. + dynamic_thresholding_ratio (`float`, defaults to 0.995): + The ratio for the dynamic thresholding method. Valid only when `thresholding=True`. + sample_max_value (`float`, defaults to 1.0): + The threshold value for dynamic thresholding. Valid only when `thresholding=True`. + timestep_spacing (`str`, defaults to `"leading"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + rescale_betas_zero_snr (`bool`, defaults to `False`): + Whether to rescale the betas to have zero terminal SNR. This enables the model to generate very bright and + dark samples instead of limiting it to samples with medium brightness. Loosely related to + [`--offset_noise`](https://github.com/huggingface/diffusers/blob/74fd735eb073eb1d774b1ab4154a0876eb82f055/examples/dreambooth/train_dreambooth.py#L506). + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + clip_sample: bool = True, + set_alpha_to_one: bool = True, + steps_offset: int = 0, + prediction_type: str = "epsilon", + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + clip_sample_range: float = 1.0, + sample_max_value: float = 1.0, + timestep_spacing: str = "leading", + rescale_betas_zero_snr: bool = False, + ): + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + # Rescale for zero SNR + if rescale_betas_zero_snr: + self.betas = rescale_zero_terminal_snr(self.betas) + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + # At every step in ddim, we are looking into the previous alphas_cumprod + # For the final step, there is no previous alphas_cumprod because we are already at 0 + # `set_alpha_to_one` decides whether we set this parameter simply to one or + # whether we use the final alpha of the "non-previous" one. + self.final_alpha_cumprod = torch.tensor(1.0) if set_alpha_to_one else self.alphas_cumprod[0] + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # setable values + self.num_inference_steps = None + self.timesteps = torch.from_numpy(np.arange(0, num_train_timesteps)[::-1].copy().astype(np.int64)) + + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + def _get_variance(self, timestep, prev_timestep): + alpha_prod_t = self.alphas_cumprod[timestep] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + variance = (beta_prod_t_prev / beta_prod_t) * (1 - alpha_prod_t / alpha_prod_t_prev) + + return variance + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler._threshold_sample + def _threshold_sample(self, sample: torch.Tensor) -> torch.Tensor: + """ + "Dynamic thresholding: At each sampling step we set s to a certain percentile absolute pixel value in xt0 (the + prediction of x_0 at timestep t), and if s > 1, then we threshold xt0 to the range [-s, s] and then divide by + s. Dynamic thresholding pushes saturated pixels (those near -1 and 1) inwards, thereby actively preventing + pixels from saturation at each step. We find that dynamic thresholding results in significantly better + photorealism as well as better image-text alignment, especially when using very large guidance weights." + + https://huggingface.co/papers/2205.11487 + """ + dtype = sample.dtype + batch_size, channels, *remaining_dims = sample.shape + + if dtype not in (torch.float32, torch.float64): + sample = sample.float() # upcast for quantile calculation, and clamp not implemented for cpu half + + # Flatten sample for doing quantile calculation along each image + sample = sample.reshape(batch_size, channels * np.prod(remaining_dims)) + + abs_sample = sample.abs() # "a certain percentile absolute pixel value" + + s = torch.quantile(abs_sample, self.config.dynamic_thresholding_ratio, dim=1) + s = torch.clamp( + s, min=1, max=self.config.sample_max_value + ) # When clamped to min=1, equivalent to standard clipping to [-1, 1] + s = s.unsqueeze(1) # (batch_size, 1) because clamp will broadcast along dim=0 + sample = torch.clamp(sample, -s, s) / s # "we threshold xt0 to the range [-s, s] and then divide by s" + + sample = sample.reshape(batch_size, channels, *remaining_dims) + sample = sample.to(dtype) + + return sample + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + """ + + if num_inference_steps > self.config.num_train_timesteps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `self.config.train_timesteps`:" + f" {self.config.num_train_timesteps} as the unet model trained with this scheduler can only handle" + f" maximal {self.config.num_train_timesteps} timesteps." + ) + + self.num_inference_steps = num_inference_steps + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = ( + np.linspace(0, self.config.num_train_timesteps - 1, num_inference_steps) + .round()[::-1] + .copy() + .astype(np.int64) + ) + elif self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.int64) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = np.round(np.arange(self.config.num_train_timesteps, 0, -step_ratio)).astype(np.int64) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'leading' or 'trailing'." + ) + + self.timesteps = torch.from_numpy(timesteps).to(device) + + def step( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + eta: float = 0.0, + use_clipped_model_output: bool = False, + generator=None, + variance_noise: Optional[torch.Tensor] = None, + return_dict: bool = True, + ) -> Union[DDIMSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + eta (`float`): + The weight of noise for added noise in diffusion step. + use_clipped_model_output (`bool`, defaults to `False`): + If `True`, computes "corrected" `model_output` from the clipped predicted original sample. Necessary + because predicted original sample is clipped to [-1, 1] when `self.config.clip_sample` is `True`. If no + clipping has happened, "corrected" `model_output` would coincide with the one provided as input and + `use_clipped_model_output` has no effect. + generator (`torch.Generator`, *optional*): + A random number generator. + variance_noise (`torch.Tensor`): + Alternative to generating noise with `generator` by directly providing the noise for the variance + itself. Useful for methods such as [`CycleDiffusion`]. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_ddim.DDIMSchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_ddim.DDIMSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_ddim.DDIMSchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + # See formulas (12) and (16) of DDIM paper https://huggingface.co/papers/2010.02502 + # Ideally, read DDIM paper in-detail understanding + + # Notation ( -> + # - pred_noise_t -> e_theta(x_t, t) + # - pred_original_sample -> f_theta(x_t, t) or x_0 + # - std_dev_t -> sigma_t + # - eta -> η + # - pred_sample_direction -> "direction pointing to x_t" + # - pred_prev_sample -> "x_t-1" + + # 1. get previous step value (=t-1) + prev_timestep = timestep - self.config.num_train_timesteps // self.num_inference_steps + + # 2. compute alphas, betas + alpha_prod_t = self.alphas_cumprod[timestep] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + + beta_prod_t = 1 - alpha_prod_t + + # 3. compute predicted original sample from predicted noise also called + # "predicted x_0" of formula (12) from https://huggingface.co/papers/2010.02502 + if self.config.prediction_type == "epsilon": + pred_original_sample = (sample - beta_prod_t ** (0.5) * model_output) / alpha_prod_t ** (0.5) + pred_epsilon = model_output + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + pred_epsilon = (sample - alpha_prod_t ** (0.5) * pred_original_sample) / beta_prod_t ** (0.5) + elif self.config.prediction_type == "v_prediction": + pred_original_sample = (alpha_prod_t**0.5) * sample - (beta_prod_t**0.5) * model_output + pred_epsilon = (alpha_prod_t**0.5) * model_output + (beta_prod_t**0.5) * sample + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, or" + " `v_prediction`" + ) + + # 4. Clip or threshold "predicted x_0" + if self.config.thresholding: + pred_original_sample = self._threshold_sample(pred_original_sample) + elif self.config.clip_sample: + pred_original_sample = pred_original_sample.clamp( + -self.config.clip_sample_range, self.config.clip_sample_range + ) + + # 5. compute variance: "sigma_t(η)" -> see formula (16) + # σ_t = sqrt((1 − α_t−1)/(1 − α_t)) * sqrt(1 − α_t/α_t−1) + variance = self._get_variance(timestep, prev_timestep) + std_dev_t = eta * variance ** (0.5) + + if use_clipped_model_output: + # the pred_epsilon is always re-derived from the clipped x_0 in Glide + pred_epsilon = (sample - alpha_prod_t ** (0.5) * pred_original_sample) / beta_prod_t ** (0.5) + + # 6. compute "direction pointing to x_t" of formula (12) from https://huggingface.co/papers/2010.02502 + pred_sample_direction = (1 - alpha_prod_t_prev - std_dev_t**2) ** (0.5) * pred_epsilon + + # 7. compute x_t without "random noise" of formula (12) from https://huggingface.co/papers/2010.02502 + prev_sample = alpha_prod_t_prev ** (0.5) * pred_original_sample + pred_sample_direction + + if eta > 0: + if variance_noise is not None and generator is not None: + raise ValueError( + "Cannot pass both generator and variance_noise. Please make sure that either `generator` or" + " `variance_noise` stays `None`." + ) + + if variance_noise is None: + variance_noise = randn_tensor( + model_output.shape, generator=generator, device=model_output.device, dtype=model_output.dtype + ) + variance = std_dev_t * variance_noise + + prev_sample = prev_sample + variance + + if not return_dict: + return ( + prev_sample, + pred_original_sample, + ) + + return DDIMSchedulerOutput(prev_sample=prev_sample, pred_original_sample=pred_original_sample) + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as original_samples + # Move the self.alphas_cumprod to device to avoid redundant CPU to GPU data movement + # for the subsequent add_noise calls + self.alphas_cumprod = self.alphas_cumprod.to(device=original_samples.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=original_samples.dtype) + timesteps = timesteps.to(original_samples.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(original_samples.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(original_samples.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + noisy_samples = sqrt_alpha_prod * original_samples + sqrt_one_minus_alpha_prod * noise + return noisy_samples + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.get_velocity + def get_velocity(self, sample: torch.Tensor, noise: torch.Tensor, timesteps: torch.IntTensor) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as sample + self.alphas_cumprod = self.alphas_cumprod.to(device=sample.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=sample.dtype) + timesteps = timesteps.to(sample.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(sample.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(sample.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + velocity = sqrt_alpha_prod * noise - sqrt_one_minus_alpha_prod * sample + return velocity + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim_cogvideox.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim_cogvideox.py new file mode 100644 index 0000000000000000000000000000000000000000..d82de8b43f5b049f96998d58c861e5f84aafb76e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim_cogvideox.py @@ -0,0 +1,452 @@ +# Copyright 2024 The CogVideoX team, Tsinghua University & ZhipuAI and The HuggingFace Team. +# All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This code is strongly influenced by https://github.com/pesser/pytorch_diffusion +# and https://github.com/hojonathanho/diffusion + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->DDIM +class DDIMSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +def rescale_zero_terminal_snr(alphas_cumprod): + """ + Rescales betas to have zero terminal SNR Based on https://huggingface.co/papers/2305.08891 (Algorithm 1) + + + Args: + betas (`torch.Tensor`): + the betas that the scheduler is being initialized with. + + Returns: + `torch.Tensor`: rescaled betas with zero terminal SNR + """ + + alphas_bar_sqrt = alphas_cumprod.sqrt() + + # Store old values. + alphas_bar_sqrt_0 = alphas_bar_sqrt[0].clone() + alphas_bar_sqrt_T = alphas_bar_sqrt[-1].clone() + + # Shift so the last timestep is zero. + alphas_bar_sqrt -= alphas_bar_sqrt_T + + # Scale so the first timestep is back to the old value. + alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T) + + # Convert alphas_bar_sqrt to betas + alphas_bar = alphas_bar_sqrt**2 # Revert sqrt + + return alphas_bar + + +class CogVideoXDDIMScheduler(SchedulerMixin, ConfigMixin): + """ + `DDIMScheduler` extends the denoising procedure introduced in denoising diffusion probabilistic models (DDPMs) with + non-Markovian guidance. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + clip_sample (`bool`, defaults to `True`): + Clip the predicted sample for numerical stability. + clip_sample_range (`float`, defaults to 1.0): + The maximum magnitude for sample clipping. Valid only when `clip_sample=True`. + set_alpha_to_one (`bool`, defaults to `True`): + Each diffusion step uses the alphas product value at that step and at the previous one. For the final step + there is no previous alpha. When this option is `True` the previous alpha product is fixed to `1`, + otherwise it uses the alpha value at step 0. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + thresholding (`bool`, defaults to `False`): + Whether to use the "dynamic thresholding" method. This is unsuitable for latent-space diffusion models such + as Stable Diffusion. + dynamic_thresholding_ratio (`float`, defaults to 0.995): + The ratio for the dynamic thresholding method. Valid only when `thresholding=True`. + sample_max_value (`float`, defaults to 1.0): + The threshold value for dynamic thresholding. Valid only when `thresholding=True`. + timestep_spacing (`str`, defaults to `"leading"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + rescale_betas_zero_snr (`bool`, defaults to `False`): + Whether to rescale the betas to have zero terminal SNR. This enables the model to generate very bright and + dark samples instead of limiting it to samples with medium brightness. Loosely related to + [`--offset_noise`](https://github.com/huggingface/diffusers/blob/74fd735eb073eb1d774b1ab4154a0876eb82f055/examples/dreambooth/train_dreambooth.py#L506). + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.00085, + beta_end: float = 0.0120, + beta_schedule: str = "scaled_linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + clip_sample: bool = True, + set_alpha_to_one: bool = True, + steps_offset: int = 0, + prediction_type: str = "epsilon", + clip_sample_range: float = 1.0, + sample_max_value: float = 1.0, + timestep_spacing: str = "leading", + rescale_betas_zero_snr: bool = False, + snr_shift_scale: float = 3.0, + ): + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float64) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + # Modify: SNR shift following SD3 + self.alphas_cumprod = self.alphas_cumprod / (snr_shift_scale + (1 - snr_shift_scale) * self.alphas_cumprod) + + # Rescale for zero SNR + if rescale_betas_zero_snr: + self.alphas_cumprod = rescale_zero_terminal_snr(self.alphas_cumprod) + + # At every step in ddim, we are looking into the previous alphas_cumprod + # For the final step, there is no previous alphas_cumprod because we are already at 0 + # `set_alpha_to_one` decides whether we set this parameter simply to one or + # whether we use the final alpha of the "non-previous" one. + self.final_alpha_cumprod = torch.tensor(1.0) if set_alpha_to_one else self.alphas_cumprod[0] + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # setable values + self.num_inference_steps = None + self.timesteps = torch.from_numpy(np.arange(0, num_train_timesteps)[::-1].copy().astype(np.int64)) + + def _get_variance(self, timestep, prev_timestep): + alpha_prod_t = self.alphas_cumprod[timestep] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + variance = (beta_prod_t_prev / beta_prod_t) * (1 - alpha_prod_t / alpha_prod_t_prev) + + return variance + + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + """ + + if num_inference_steps > self.config.num_train_timesteps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `self.config.train_timesteps`:" + f" {self.config.num_train_timesteps} as the unet model trained with this scheduler can only handle" + f" maximal {self.config.num_train_timesteps} timesteps." + ) + + self.num_inference_steps = num_inference_steps + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = ( + np.linspace(0, self.config.num_train_timesteps - 1, num_inference_steps) + .round()[::-1] + .copy() + .astype(np.int64) + ) + elif self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.int64) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = np.round(np.arange(self.config.num_train_timesteps, 0, -step_ratio)).astype(np.int64) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'leading' or 'trailing'." + ) + + self.timesteps = torch.from_numpy(timesteps).to(device) + + def step( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + eta: float = 0.0, + use_clipped_model_output: bool = False, + generator=None, + variance_noise: Optional[torch.Tensor] = None, + return_dict: bool = True, + ) -> Union[DDIMSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + eta (`float`): + The weight of noise for added noise in diffusion step. + use_clipped_model_output (`bool`, defaults to `False`): + If `True`, computes "corrected" `model_output` from the clipped predicted original sample. Necessary + because predicted original sample is clipped to [-1, 1] when `self.config.clip_sample` is `True`. If no + clipping has happened, "corrected" `model_output` would coincide with the one provided as input and + `use_clipped_model_output` has no effect. + generator (`torch.Generator`, *optional*): + A random number generator. + variance_noise (`torch.Tensor`): + Alternative to generating noise with `generator` by directly providing the noise for the variance + itself. Useful for methods such as [`CycleDiffusion`]. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_ddim.DDIMSchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_ddim.DDIMSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_ddim.DDIMSchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + # See formulas (12) and (16) of DDIM paper https://huggingface.co/papers/2010.02502 + # Ideally, read DDIM paper in-detail understanding + + # Notation ( -> + # - pred_noise_t -> e_theta(x_t, t) + # - pred_original_sample -> f_theta(x_t, t) or x_0 + # - std_dev_t -> sigma_t + # - eta -> η + # - pred_sample_direction -> "direction pointing to x_t" + # - pred_prev_sample -> "x_t-1" + + # 1. get previous step value (=t-1) + prev_timestep = timestep - self.config.num_train_timesteps // self.num_inference_steps + + # 2. compute alphas, betas + alpha_prod_t = self.alphas_cumprod[timestep] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + + beta_prod_t = 1 - alpha_prod_t + + # 3. compute predicted original sample from predicted noise also called + # "predicted x_0" of formula (12) from https://huggingface.co/papers/2010.02502 + # To make style tests pass, commented out `pred_epsilon` as it is an unused variable + if self.config.prediction_type == "epsilon": + pred_original_sample = (sample - beta_prod_t ** (0.5) * model_output) / alpha_prod_t ** (0.5) + # pred_epsilon = model_output + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + # pred_epsilon = (sample - alpha_prod_t ** (0.5) * pred_original_sample) / beta_prod_t ** (0.5) + elif self.config.prediction_type == "v_prediction": + pred_original_sample = (alpha_prod_t**0.5) * sample - (beta_prod_t**0.5) * model_output + # pred_epsilon = (alpha_prod_t**0.5) * model_output + (beta_prod_t**0.5) * sample + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, or" + " `v_prediction`" + ) + + a_t = ((1 - alpha_prod_t_prev) / (1 - alpha_prod_t)) ** 0.5 + b_t = alpha_prod_t_prev**0.5 - alpha_prod_t**0.5 * a_t + + prev_sample = a_t * sample + b_t * pred_original_sample + + if not return_dict: + return ( + prev_sample, + pred_original_sample, + ) + + return DDIMSchedulerOutput(prev_sample=prev_sample, pred_original_sample=pred_original_sample) + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as original_samples + # Move the self.alphas_cumprod to device to avoid redundant CPU to GPU data movement + # for the subsequent add_noise calls + self.alphas_cumprod = self.alphas_cumprod.to(device=original_samples.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=original_samples.dtype) + timesteps = timesteps.to(original_samples.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(original_samples.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(original_samples.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + noisy_samples = sqrt_alpha_prod * original_samples + sqrt_one_minus_alpha_prod * noise + return noisy_samples + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.get_velocity + def get_velocity(self, sample: torch.Tensor, noise: torch.Tensor, timesteps: torch.IntTensor) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as sample + self.alphas_cumprod = self.alphas_cumprod.to(device=sample.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=sample.dtype) + timesteps = timesteps.to(sample.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(sample.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(sample.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + velocity = sqrt_alpha_prod * noise - sqrt_one_minus_alpha_prod * sample + return velocity + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim_flax.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim_flax.py new file mode 100644 index 0000000000000000000000000000000000000000..6ccf35628bc23226a5b0d1c80c7e2f8c9007a48c --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim_flax.py @@ -0,0 +1,314 @@ +# Copyright 2024 Stanford University Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This code is strongly influenced by https://github.com/pesser/pytorch_diffusion +# and https://github.com/hojonathanho/diffusion + +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import flax +import jax.numpy as jnp + +from ..configuration_utils import ConfigMixin, register_to_config +from .scheduling_utils_flax import ( + CommonSchedulerState, + FlaxKarrasDiffusionSchedulers, + FlaxSchedulerMixin, + FlaxSchedulerOutput, + add_noise_common, + get_velocity_common, +) + + +@flax.struct.dataclass +class DDIMSchedulerState: + common: CommonSchedulerState + final_alpha_cumprod: jnp.ndarray + + # setable values + init_noise_sigma: jnp.ndarray + timesteps: jnp.ndarray + num_inference_steps: Optional[int] = None + + @classmethod + def create( + cls, + common: CommonSchedulerState, + final_alpha_cumprod: jnp.ndarray, + init_noise_sigma: jnp.ndarray, + timesteps: jnp.ndarray, + ): + return cls( + common=common, + final_alpha_cumprod=final_alpha_cumprod, + init_noise_sigma=init_noise_sigma, + timesteps=timesteps, + ) + + +@dataclass +class FlaxDDIMSchedulerOutput(FlaxSchedulerOutput): + state: DDIMSchedulerState + + +class FlaxDDIMScheduler(FlaxSchedulerMixin, ConfigMixin): + """ + Denoising diffusion implicit models is a scheduler that extends the denoising procedure introduced in denoising + diffusion probabilistic models (DDPMs) with non-Markovian guidance. + + [`~ConfigMixin`] takes care of storing all config attributes that are passed in the scheduler's `__init__` + function, such as `num_train_timesteps`. They can be accessed via `scheduler.config.num_train_timesteps`. + [`SchedulerMixin`] provides general loading and saving functionality via the [`SchedulerMixin.save_pretrained`] and + [`~SchedulerMixin.from_pretrained`] functions. + + For more details, see the original paper: https://huggingface.co/papers/2010.02502 + + Args: + num_train_timesteps (`int`): number of diffusion steps used to train the model. + beta_start (`float`): the starting `beta` value of inference. + beta_end (`float`): the final `beta` value. + beta_schedule (`str`): + the beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`jnp.ndarray`, optional): + option to pass an array of betas directly to the constructor to bypass `beta_start`, `beta_end` etc. + clip_sample (`bool`, default `True`): + option to clip predicted sample between for numerical stability. The clip range is determined by + `clip_sample_range`. + clip_sample_range (`float`, default `1.0`): + the maximum magnitude for sample clipping. Valid only when `clip_sample=True`. + set_alpha_to_one (`bool`, default `True`): + each diffusion step uses the value of alphas product at that step and at the previous one. For the final + step there is no previous alpha. When this option is `True` the previous alpha product is fixed to `1`, + otherwise it uses the value of alpha at step 0. + steps_offset (`int`, default `0`): + An offset added to the inference steps, as required by some model families. + prediction_type (`str`, default `epsilon`): + indicates whether the model predicts the noise (epsilon), or the samples. One of `epsilon`, `sample`. + `v-prediction` is not supported for this scheduler. + dtype (`jnp.dtype`, *optional*, defaults to `jnp.float32`): + the `dtype` used for params and computation. + """ + + _compatibles = [e.name for e in FlaxKarrasDiffusionSchedulers] + + dtype: jnp.dtype + + @property + def has_state(self): + return True + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[jnp.ndarray] = None, + clip_sample: bool = True, + clip_sample_range: float = 1.0, + set_alpha_to_one: bool = True, + steps_offset: int = 0, + prediction_type: str = "epsilon", + dtype: jnp.dtype = jnp.float32, + ): + self.dtype = dtype + + def create_state(self, common: Optional[CommonSchedulerState] = None) -> DDIMSchedulerState: + if common is None: + common = CommonSchedulerState.create(self) + + # At every step in ddim, we are looking into the previous alphas_cumprod + # For the final step, there is no previous alphas_cumprod because we are already at 0 + # `set_alpha_to_one` decides whether we set this parameter simply to one or + # whether we use the final alpha of the "non-previous" one. + final_alpha_cumprod = ( + jnp.array(1.0, dtype=self.dtype) if self.config.set_alpha_to_one else common.alphas_cumprod[0] + ) + + # standard deviation of the initial noise distribution + init_noise_sigma = jnp.array(1.0, dtype=self.dtype) + + timesteps = jnp.arange(0, self.config.num_train_timesteps).round()[::-1] + + return DDIMSchedulerState.create( + common=common, + final_alpha_cumprod=final_alpha_cumprod, + init_noise_sigma=init_noise_sigma, + timesteps=timesteps, + ) + + def scale_model_input( + self, state: DDIMSchedulerState, sample: jnp.ndarray, timestep: Optional[int] = None + ) -> jnp.ndarray: + """ + Args: + state (`PNDMSchedulerState`): the `FlaxPNDMScheduler` state data class instance. + sample (`jnp.ndarray`): input sample + timestep (`int`, optional): current timestep + + Returns: + `jnp.ndarray`: scaled input sample + """ + return sample + + def set_timesteps( + self, state: DDIMSchedulerState, num_inference_steps: int, shape: Tuple = () + ) -> DDIMSchedulerState: + """ + Sets the discrete timesteps used for the diffusion chain. Supporting function to be run before inference. + + Args: + state (`DDIMSchedulerState`): + the `FlaxDDIMScheduler` state data class instance. + num_inference_steps (`int`): + the number of diffusion steps used when generating samples with a pre-trained model. + """ + step_ratio = self.config.num_train_timesteps // num_inference_steps + # creates integer timesteps by multiplying by ratio + # rounding to avoid issues when num_inference_step is power of 3 + timesteps = (jnp.arange(0, num_inference_steps) * step_ratio).round()[::-1] + self.config.steps_offset + + return state.replace( + num_inference_steps=num_inference_steps, + timesteps=timesteps, + ) + + def _get_variance(self, state: DDIMSchedulerState, timestep, prev_timestep): + alpha_prod_t = state.common.alphas_cumprod[timestep] + alpha_prod_t_prev = jnp.where( + prev_timestep >= 0, state.common.alphas_cumprod[prev_timestep], state.final_alpha_cumprod + ) + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + variance = (beta_prod_t_prev / beta_prod_t) * (1 - alpha_prod_t / alpha_prod_t_prev) + + return variance + + def step( + self, + state: DDIMSchedulerState, + model_output: jnp.ndarray, + timestep: int, + sample: jnp.ndarray, + eta: float = 0.0, + return_dict: bool = True, + ) -> Union[FlaxDDIMSchedulerOutput, Tuple]: + """ + Predict the sample at the previous timestep by reversing the SDE. Core function to propagate the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + state (`DDIMSchedulerState`): the `FlaxDDIMScheduler` state data class instance. + model_output (`jnp.ndarray`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + return_dict (`bool`): option for returning tuple rather than FlaxDDIMSchedulerOutput class + + Returns: + [`FlaxDDIMSchedulerOutput`] or `tuple`: [`FlaxDDIMSchedulerOutput`] if `return_dict` is True, otherwise a + `tuple`. When returning a tuple, the first element is the sample tensor. + + """ + if state.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + # See formulas (12) and (16) of DDIM paper https://huggingface.co/papers/2010.02502 + # Ideally, read DDIM paper in-detail understanding + + # Notation ( -> + # - pred_noise_t -> e_theta(x_t, t) + # - pred_original_sample -> f_theta(x_t, t) or x_0 + # - std_dev_t -> sigma_t + # - eta -> η + # - pred_sample_direction -> "direction pointing to x_t" + # - pred_prev_sample -> "x_t-1" + + # 1. get previous step value (=t-1) + prev_timestep = timestep - self.config.num_train_timesteps // state.num_inference_steps + + alphas_cumprod = state.common.alphas_cumprod + final_alpha_cumprod = state.final_alpha_cumprod + + # 2. compute alphas, betas + alpha_prod_t = alphas_cumprod[timestep] + alpha_prod_t_prev = jnp.where(prev_timestep >= 0, alphas_cumprod[prev_timestep], final_alpha_cumprod) + + beta_prod_t = 1 - alpha_prod_t + + # 3. compute predicted original sample from predicted noise also called + # "predicted x_0" of formula (12) from https://huggingface.co/papers/2010.02502 + if self.config.prediction_type == "epsilon": + pred_original_sample = (sample - beta_prod_t ** (0.5) * model_output) / alpha_prod_t ** (0.5) + pred_epsilon = model_output + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + pred_epsilon = (sample - alpha_prod_t ** (0.5) * pred_original_sample) / beta_prod_t ** (0.5) + elif self.config.prediction_type == "v_prediction": + pred_original_sample = (alpha_prod_t**0.5) * sample - (beta_prod_t**0.5) * model_output + pred_epsilon = (alpha_prod_t**0.5) * model_output + (beta_prod_t**0.5) * sample + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, or" + " `v_prediction`" + ) + + # 4. Clip or threshold "predicted x_0" + if self.config.clip_sample: + pred_original_sample = pred_original_sample.clip( + -self.config.clip_sample_range, self.config.clip_sample_range + ) + + # 4. compute variance: "sigma_t(η)" -> see formula (16) + # σ_t = sqrt((1 − α_t−1)/(1 − α_t)) * sqrt(1 − α_t/α_t−1) + variance = self._get_variance(state, timestep, prev_timestep) + std_dev_t = eta * variance ** (0.5) + + # 5. compute "direction pointing to x_t" of formula (12) from https://huggingface.co/papers/2010.02502 + pred_sample_direction = (1 - alpha_prod_t_prev - std_dev_t**2) ** (0.5) * pred_epsilon + + # 6. compute x_t without "random noise" of formula (12) from https://huggingface.co/papers/2010.02502 + prev_sample = alpha_prod_t_prev ** (0.5) * pred_original_sample + pred_sample_direction + + if not return_dict: + return (prev_sample, state) + + return FlaxDDIMSchedulerOutput(prev_sample=prev_sample, state=state) + + def add_noise( + self, + state: DDIMSchedulerState, + original_samples: jnp.ndarray, + noise: jnp.ndarray, + timesteps: jnp.ndarray, + ) -> jnp.ndarray: + return add_noise_common(state.common, original_samples, noise, timesteps) + + def get_velocity( + self, + state: DDIMSchedulerState, + sample: jnp.ndarray, + noise: jnp.ndarray, + timesteps: jnp.ndarray, + ) -> jnp.ndarray: + return get_velocity_common(state.common, sample, noise, timesteps) + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim_inverse.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim_inverse.py new file mode 100644 index 0000000000000000000000000000000000000000..b0caf630da19331ae96403cdf62f9728d146e014 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim_inverse.py @@ -0,0 +1,374 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This code is strongly influenced by https://github.com/pesser/pytorch_diffusion +# and https://github.com/hojonathanho/diffusion +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from diffusers.configuration_utils import ConfigMixin, register_to_config +from diffusers.schedulers.scheduling_utils import SchedulerMixin +from diffusers.utils import BaseOutput, deprecate + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->DDIM +class DDIMSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +# Copied from diffusers.schedulers.scheduling_ddim.rescale_zero_terminal_snr +def rescale_zero_terminal_snr(betas): + """ + Rescales betas to have zero terminal SNR Based on https://huggingface.co/papers/2305.08891 (Algorithm 1) + + + Args: + betas (`torch.Tensor`): + the betas that the scheduler is being initialized with. + + Returns: + `torch.Tensor`: rescaled betas with zero terminal SNR + """ + # Convert betas to alphas_bar_sqrt + alphas = 1.0 - betas + alphas_cumprod = torch.cumprod(alphas, dim=0) + alphas_bar_sqrt = alphas_cumprod.sqrt() + + # Store old values. + alphas_bar_sqrt_0 = alphas_bar_sqrt[0].clone() + alphas_bar_sqrt_T = alphas_bar_sqrt[-1].clone() + + # Shift so the last timestep is zero. + alphas_bar_sqrt -= alphas_bar_sqrt_T + + # Scale so the first timestep is back to the old value. + alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T) + + # Convert alphas_bar_sqrt to betas + alphas_bar = alphas_bar_sqrt**2 # Revert sqrt + alphas = alphas_bar[1:] / alphas_bar[:-1] # Revert cumprod + alphas = torch.cat([alphas_bar[0:1], alphas]) + betas = 1 - alphas + + return betas + + +class DDIMInverseScheduler(SchedulerMixin, ConfigMixin): + """ + `DDIMInverseScheduler` is the reverse scheduler of [`DDIMScheduler`]. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + clip_sample (`bool`, defaults to `True`): + Clip the predicted sample for numerical stability. + clip_sample_range (`float`, defaults to 1.0): + The maximum magnitude for sample clipping. Valid only when `clip_sample=True`. + set_alpha_to_one (`bool`, defaults to `True`): + Each diffusion step uses the alphas product value at that step and at the previous one. For the final step + there is no previous alpha. When this option is `True` the previous alpha product is fixed to 0, otherwise + it uses the alpha value at step `num_train_timesteps - 1`. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + timestep_spacing (`str`, defaults to `"leading"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + rescale_betas_zero_snr (`bool`, defaults to `False`): + Whether to rescale the betas to have zero terminal SNR. This enables the model to generate very bright and + dark samples instead of limiting it to samples with medium brightness. Loosely related to + [`--offset_noise`](https://github.com/huggingface/diffusers/blob/74fd735eb073eb1d774b1ab4154a0876eb82f055/examples/dreambooth/train_dreambooth.py#L506). + """ + + order = 1 + ignore_for_config = ["kwargs"] + _deprecated_kwargs = ["set_alpha_to_zero"] + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + clip_sample: bool = True, + set_alpha_to_one: bool = True, + steps_offset: int = 0, + prediction_type: str = "epsilon", + clip_sample_range: float = 1.0, + timestep_spacing: str = "leading", + rescale_betas_zero_snr: bool = False, + **kwargs, + ): + if kwargs.get("set_alpha_to_zero", None) is not None: + deprecation_message = ( + "The `set_alpha_to_zero` argument is deprecated. Please use `set_alpha_to_one` instead." + ) + deprecate("set_alpha_to_zero", "1.0.0", deprecation_message, standard_warn=False) + set_alpha_to_one = kwargs["set_alpha_to_zero"] + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + # Rescale for zero SNR + if rescale_betas_zero_snr: + self.betas = rescale_zero_terminal_snr(self.betas) + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + # At every step in inverted ddim, we are looking into the next alphas_cumprod + # For the initial step, there is no current alphas_cumprod, and the index is out of bounds + # `set_alpha_to_one` decides whether we set this parameter simply to one + # in this case, self.step() just output the predicted noise + # or whether we use the initial alpha used in training the diffusion model. + self.initial_alpha_cumprod = torch.tensor(1.0) if set_alpha_to_one else self.alphas_cumprod[0] + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # setable values + self.num_inference_steps = None + self.timesteps = torch.from_numpy(np.arange(0, num_train_timesteps).copy().astype(np.int64)) + + # Copied from diffusers.schedulers.scheduling_ddim.DDIMScheduler.scale_model_input + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + """ + + if num_inference_steps > self.config.num_train_timesteps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `self.config.train_timesteps`:" + f" {self.config.num_train_timesteps} as the unet model trained with this scheduler can only handle" + f" maximal {self.config.num_train_timesteps} timesteps." + ) + + self.num_inference_steps = num_inference_steps + + # "leading" and "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round().copy().astype(np.int64) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = np.round(np.arange(self.config.num_train_timesteps, 0, -step_ratio)[::-1]).astype(np.int64) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'leading' or 'trailing'." + ) + + self.timesteps = torch.from_numpy(timesteps).to(device) + + def step( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + return_dict: bool = True, + ) -> Union[DDIMSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + eta (`float`): + The weight of noise for added noise in diffusion step. + use_clipped_model_output (`bool`, defaults to `False`): + If `True`, computes "corrected" `model_output` from the clipped predicted original sample. Necessary + because predicted original sample is clipped to [-1, 1] when `self.config.clip_sample` is `True`. If no + clipping has happened, "corrected" `model_output` would coincide with the one provided as input and + `use_clipped_model_output` has no effect. + variance_noise (`torch.Tensor`): + Alternative to generating noise with `generator` by directly providing the noise for the variance + itself. Useful for methods such as [`CycleDiffusion`]. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_ddim_inverse.DDIMInverseSchedulerOutput`] or + `tuple`. + + Returns: + [`~schedulers.scheduling_ddim_inverse.DDIMInverseSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_ddim_inverse.DDIMInverseSchedulerOutput`] is + returned, otherwise a tuple is returned where the first element is the sample tensor. + + """ + # 1. get previous step value (=t+1) + prev_timestep = timestep + timestep = min( + timestep - self.config.num_train_timesteps // self.num_inference_steps, self.config.num_train_timesteps - 1 + ) + + # 2. compute alphas, betas + # change original implementation to exactly match noise levels for analogous forward process + alpha_prod_t = self.alphas_cumprod[timestep] if timestep >= 0 else self.initial_alpha_cumprod + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] + + beta_prod_t = 1 - alpha_prod_t + + # 3. compute predicted original sample from predicted noise also called + # "predicted x_0" of formula (12) from https://huggingface.co/papers/2010.02502 + if self.config.prediction_type == "epsilon": + pred_original_sample = (sample - beta_prod_t ** (0.5) * model_output) / alpha_prod_t ** (0.5) + pred_epsilon = model_output + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + pred_epsilon = (sample - alpha_prod_t ** (0.5) * pred_original_sample) / beta_prod_t ** (0.5) + elif self.config.prediction_type == "v_prediction": + pred_original_sample = (alpha_prod_t**0.5) * sample - (beta_prod_t**0.5) * model_output + pred_epsilon = (alpha_prod_t**0.5) * model_output + (beta_prod_t**0.5) * sample + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, or" + " `v_prediction`" + ) + + # 4. Clip or threshold "predicted x_0" + if self.config.clip_sample: + pred_original_sample = pred_original_sample.clamp( + -self.config.clip_sample_range, self.config.clip_sample_range + ) + + # 5. compute "direction pointing to x_t" of formula (12) from https://huggingface.co/papers/2010.02502 + pred_sample_direction = (1 - alpha_prod_t_prev) ** (0.5) * pred_epsilon + + # 6. compute x_t without "random noise" of formula (12) from https://huggingface.co/papers/2010.02502 + prev_sample = alpha_prod_t_prev ** (0.5) * pred_original_sample + pred_sample_direction + + if not return_dict: + return (prev_sample, pred_original_sample) + return DDIMSchedulerOutput(prev_sample=prev_sample, pred_original_sample=pred_original_sample) + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim_parallel.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim_parallel.py new file mode 100644 index 0000000000000000000000000000000000000000..54404a33062c9c0e8272566801f0f53b39db7966 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddim_parallel.py @@ -0,0 +1,646 @@ +# Copyright 2024 ParaDiGMS authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This code is strongly influenced by https://github.com/pesser/pytorch_diffusion +# and https://github.com/hojonathanho/diffusion + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput +class DDIMParallelSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +# Copied from diffusers.schedulers.scheduling_ddim.rescale_zero_terminal_snr +def rescale_zero_terminal_snr(betas): + """ + Rescales betas to have zero terminal SNR Based on https://huggingface.co/papers/2305.08891 (Algorithm 1) + + + Args: + betas (`torch.Tensor`): + the betas that the scheduler is being initialized with. + + Returns: + `torch.Tensor`: rescaled betas with zero terminal SNR + """ + # Convert betas to alphas_bar_sqrt + alphas = 1.0 - betas + alphas_cumprod = torch.cumprod(alphas, dim=0) + alphas_bar_sqrt = alphas_cumprod.sqrt() + + # Store old values. + alphas_bar_sqrt_0 = alphas_bar_sqrt[0].clone() + alphas_bar_sqrt_T = alphas_bar_sqrt[-1].clone() + + # Shift so the last timestep is zero. + alphas_bar_sqrt -= alphas_bar_sqrt_T + + # Scale so the first timestep is back to the old value. + alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T) + + # Convert alphas_bar_sqrt to betas + alphas_bar = alphas_bar_sqrt**2 # Revert sqrt + alphas = alphas_bar[1:] / alphas_bar[:-1] # Revert cumprod + alphas = torch.cat([alphas_bar[0:1], alphas]) + betas = 1 - alphas + + return betas + + +class DDIMParallelScheduler(SchedulerMixin, ConfigMixin): + """ + Denoising diffusion implicit models is a scheduler that extends the denoising procedure introduced in denoising + diffusion probabilistic models (DDPMs) with non-Markovian guidance. + + [`~ConfigMixin`] takes care of storing all config attributes that are passed in the scheduler's `__init__` + function, such as `num_train_timesteps`. They can be accessed via `scheduler.config.num_train_timesteps`. + [`SchedulerMixin`] provides general loading and saving functionality via the [`SchedulerMixin.save_pretrained`] and + [`~SchedulerMixin.from_pretrained`] functions. + + For more details, see the original paper: https://huggingface.co/papers/2010.02502 + + Args: + num_train_timesteps (`int`): number of diffusion steps used to train the model. + beta_start (`float`): the starting `beta` value of inference. + beta_end (`float`): the final `beta` value. + beta_schedule (`str`): + the beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, optional): + option to pass an array of betas directly to the constructor to bypass `beta_start`, `beta_end` etc. + clip_sample (`bool`, default `True`): + option to clip predicted sample for numerical stability. + clip_sample_range (`float`, default `1.0`): + the maximum magnitude for sample clipping. Valid only when `clip_sample=True`. + set_alpha_to_one (`bool`, default `True`): + each diffusion step uses the value of alphas product at that step and at the previous one. For the final + step there is no previous alpha. When this option is `True` the previous alpha product is fixed to `1`, + otherwise it uses the value of alpha at step 0. + steps_offset (`int`, default `0`): + An offset added to the inference steps, as required by some model families. + prediction_type (`str`, default `epsilon`, optional): + prediction type of the scheduler function, one of `epsilon` (predicting the noise of the diffusion + process), `sample` (directly predicting the noisy sample`) or `v_prediction` (see section 2.4 + https://imagen.research.google/video/paper.pdf) + thresholding (`bool`, default `False`): + whether to use the "dynamic thresholding" method (introduced by Imagen, + https://huggingface.co/papers/2205.11487). Note that the thresholding method is unsuitable for latent-space + diffusion models (such as stable-diffusion). + dynamic_thresholding_ratio (`float`, default `0.995`): + the ratio for the dynamic thresholding method. Default is `0.995`, the same as Imagen + (https://huggingface.co/papers/2205.11487). Valid only when `thresholding=True`. + sample_max_value (`float`, default `1.0`): + the threshold value for dynamic thresholding. Valid only when `thresholding=True`. + timestep_spacing (`str`, default `"leading"`): + The way the timesteps should be scaled. Refer to Table 2. of [Common Diffusion Noise Schedules and Sample + Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + rescale_betas_zero_snr (`bool`, default `False`): + whether to rescale the betas to have zero terminal SNR (proposed by + https://huggingface.co/papers/2305.08891). This can enable the model to generate very bright and dark + samples instead of limiting it to samples with medium brightness. Loosely related to + [`--offset_noise`](https://github.com/huggingface/diffusers/blob/74fd735eb073eb1d774b1ab4154a0876eb82f055/examples/dreambooth/train_dreambooth.py#L506). + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + _is_ode_scheduler = True + + @register_to_config + # Copied from diffusers.schedulers.scheduling_ddim.DDIMScheduler.__init__ + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + clip_sample: bool = True, + set_alpha_to_one: bool = True, + steps_offset: int = 0, + prediction_type: str = "epsilon", + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + clip_sample_range: float = 1.0, + sample_max_value: float = 1.0, + timestep_spacing: str = "leading", + rescale_betas_zero_snr: bool = False, + ): + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + # Rescale for zero SNR + if rescale_betas_zero_snr: + self.betas = rescale_zero_terminal_snr(self.betas) + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + # At every step in ddim, we are looking into the previous alphas_cumprod + # For the final step, there is no previous alphas_cumprod because we are already at 0 + # `set_alpha_to_one` decides whether we set this parameter simply to one or + # whether we use the final alpha of the "non-previous" one. + self.final_alpha_cumprod = torch.tensor(1.0) if set_alpha_to_one else self.alphas_cumprod[0] + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # setable values + self.num_inference_steps = None + self.timesteps = torch.from_numpy(np.arange(0, num_train_timesteps)[::-1].copy().astype(np.int64)) + + # Copied from diffusers.schedulers.scheduling_ddim.DDIMScheduler.scale_model_input + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + def _get_variance(self, timestep, prev_timestep=None): + if prev_timestep is None: + prev_timestep = timestep - self.config.num_train_timesteps // self.num_inference_steps + + alpha_prod_t = self.alphas_cumprod[timestep] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + variance = (beta_prod_t_prev / beta_prod_t) * (1 - alpha_prod_t / alpha_prod_t_prev) + + return variance + + def _batch_get_variance(self, t, prev_t): + alpha_prod_t = self.alphas_cumprod[t] + alpha_prod_t_prev = self.alphas_cumprod[torch.clip(prev_t, min=0)] + alpha_prod_t_prev[prev_t < 0] = torch.tensor(1.0) + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + variance = (beta_prod_t_prev / beta_prod_t) * (1 - alpha_prod_t / alpha_prod_t_prev) + + return variance + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler._threshold_sample + def _threshold_sample(self, sample: torch.Tensor) -> torch.Tensor: + """ + "Dynamic thresholding: At each sampling step we set s to a certain percentile absolute pixel value in xt0 (the + prediction of x_0 at timestep t), and if s > 1, then we threshold xt0 to the range [-s, s] and then divide by + s. Dynamic thresholding pushes saturated pixels (those near -1 and 1) inwards, thereby actively preventing + pixels from saturation at each step. We find that dynamic thresholding results in significantly better + photorealism as well as better image-text alignment, especially when using very large guidance weights." + + https://huggingface.co/papers/2205.11487 + """ + dtype = sample.dtype + batch_size, channels, *remaining_dims = sample.shape + + if dtype not in (torch.float32, torch.float64): + sample = sample.float() # upcast for quantile calculation, and clamp not implemented for cpu half + + # Flatten sample for doing quantile calculation along each image + sample = sample.reshape(batch_size, channels * np.prod(remaining_dims)) + + abs_sample = sample.abs() # "a certain percentile absolute pixel value" + + s = torch.quantile(abs_sample, self.config.dynamic_thresholding_ratio, dim=1) + s = torch.clamp( + s, min=1, max=self.config.sample_max_value + ) # When clamped to min=1, equivalent to standard clipping to [-1, 1] + s = s.unsqueeze(1) # (batch_size, 1) because clamp will broadcast along dim=0 + sample = torch.clamp(sample, -s, s) / s # "we threshold xt0 to the range [-s, s] and then divide by s" + + sample = sample.reshape(batch_size, channels, *remaining_dims) + sample = sample.to(dtype) + + return sample + + # Copied from diffusers.schedulers.scheduling_ddim.DDIMScheduler.set_timesteps + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + """ + + if num_inference_steps > self.config.num_train_timesteps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `self.config.train_timesteps`:" + f" {self.config.num_train_timesteps} as the unet model trained with this scheduler can only handle" + f" maximal {self.config.num_train_timesteps} timesteps." + ) + + self.num_inference_steps = num_inference_steps + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = ( + np.linspace(0, self.config.num_train_timesteps - 1, num_inference_steps) + .round()[::-1] + .copy() + .astype(np.int64) + ) + elif self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.int64) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = np.round(np.arange(self.config.num_train_timesteps, 0, -step_ratio)).astype(np.int64) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'leading' or 'trailing'." + ) + + self.timesteps = torch.from_numpy(timesteps).to(device) + + def step( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + eta: float = 0.0, + use_clipped_model_output: bool = False, + generator=None, + variance_noise: Optional[torch.Tensor] = None, + return_dict: bool = True, + ) -> Union[DDIMParallelSchedulerOutput, Tuple]: + """ + Predict the sample at the previous timestep by reversing the SDE. Core function to propagate the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + current instance of sample being created by diffusion process. + eta (`float`): weight of noise for added noise in diffusion step. + use_clipped_model_output (`bool`): if `True`, compute "corrected" `model_output` from the clipped + predicted original sample. Necessary because predicted original sample is clipped to [-1, 1] when + `self.config.clip_sample` is `True`. If no clipping has happened, "corrected" `model_output` would + coincide with the one provided as input and `use_clipped_model_output` will have not effect. + generator: random number generator. + variance_noise (`torch.Tensor`): instead of generating noise for the variance using `generator`, we + can directly provide the noise for the variance itself. This is useful for methods such as + CycleDiffusion. (https://huggingface.co/papers/2210.05559) + return_dict (`bool`): option for returning tuple rather than DDIMParallelSchedulerOutput class + + Returns: + [`~schedulers.scheduling_utils.DDIMParallelSchedulerOutput`] or `tuple`: + [`~schedulers.scheduling_utils.DDIMParallelSchedulerOutput`] if `return_dict` is True, otherwise a `tuple`. + When returning a tuple, the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + # See formulas (12) and (16) of DDIM paper https://huggingface.co/papers/2010.02502 + # Ideally, read DDIM paper in-detail understanding + + # Notation ( -> + # - pred_noise_t -> e_theta(x_t, t) + # - pred_original_sample -> f_theta(x_t, t) or x_0 + # - std_dev_t -> sigma_t + # - eta -> η + # - pred_sample_direction -> "direction pointing to x_t" + # - pred_prev_sample -> "x_t-1" + + # 1. get previous step value (=t-1) + prev_timestep = timestep - self.config.num_train_timesteps // self.num_inference_steps + + # 2. compute alphas, betas + alpha_prod_t = self.alphas_cumprod[timestep] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + + beta_prod_t = 1 - alpha_prod_t + + # 3. compute predicted original sample from predicted noise also called + # "predicted x_0" of formula (12) from https://huggingface.co/papers/2010.02502 + if self.config.prediction_type == "epsilon": + pred_original_sample = (sample - beta_prod_t ** (0.5) * model_output) / alpha_prod_t ** (0.5) + pred_epsilon = model_output + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + pred_epsilon = (sample - alpha_prod_t ** (0.5) * pred_original_sample) / beta_prod_t ** (0.5) + elif self.config.prediction_type == "v_prediction": + pred_original_sample = (alpha_prod_t**0.5) * sample - (beta_prod_t**0.5) * model_output + pred_epsilon = (alpha_prod_t**0.5) * model_output + (beta_prod_t**0.5) * sample + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, or" + " `v_prediction`" + ) + + # 4. Clip or threshold "predicted x_0" + if self.config.thresholding: + pred_original_sample = self._threshold_sample(pred_original_sample) + elif self.config.clip_sample: + pred_original_sample = pred_original_sample.clamp( + -self.config.clip_sample_range, self.config.clip_sample_range + ) + + # 5. compute variance: "sigma_t(η)" -> see formula (16) + # σ_t = sqrt((1 − α_t−1)/(1 − α_t)) * sqrt(1 − α_t/α_t−1) + variance = self._get_variance(timestep, prev_timestep) + std_dev_t = eta * variance ** (0.5) + + if use_clipped_model_output: + # the pred_epsilon is always re-derived from the clipped x_0 in Glide + pred_epsilon = (sample - alpha_prod_t ** (0.5) * pred_original_sample) / beta_prod_t ** (0.5) + + # 6. compute "direction pointing to x_t" of formula (12) from https://huggingface.co/papers/2010.02502 + pred_sample_direction = (1 - alpha_prod_t_prev - std_dev_t**2) ** (0.5) * pred_epsilon + + # 7. compute x_t without "random noise" of formula (12) from https://huggingface.co/papers/2010.02502 + prev_sample = alpha_prod_t_prev ** (0.5) * pred_original_sample + pred_sample_direction + + if eta > 0: + if variance_noise is not None and generator is not None: + raise ValueError( + "Cannot pass both generator and variance_noise. Please make sure that either `generator` or" + " `variance_noise` stays `None`." + ) + + if variance_noise is None: + variance_noise = randn_tensor( + model_output.shape, generator=generator, device=model_output.device, dtype=model_output.dtype + ) + variance = std_dev_t * variance_noise + + prev_sample = prev_sample + variance + + if not return_dict: + return ( + prev_sample, + pred_original_sample, + ) + + return DDIMParallelSchedulerOutput(prev_sample=prev_sample, pred_original_sample=pred_original_sample) + + def batch_step_no_noise( + self, + model_output: torch.Tensor, + timesteps: List[int], + sample: torch.Tensor, + eta: float = 0.0, + use_clipped_model_output: bool = False, + ) -> torch.Tensor: + """ + Batched version of the `step` function, to be able to reverse the SDE for multiple samples/timesteps at once. + Also, does not add any noise to the predicted sample, which is necessary for parallel sampling where the noise + is pre-sampled by the pipeline. + + Predict the sample at the previous timestep by reversing the SDE. Core function to propagate the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): direct output from learned diffusion model. + timesteps (`List[int]`): + current discrete timesteps in the diffusion chain. This is now a list of integers. + sample (`torch.Tensor`): + current instance of sample being created by diffusion process. + eta (`float`): weight of noise for added noise in diffusion step. + use_clipped_model_output (`bool`): if `True`, compute "corrected" `model_output` from the clipped + predicted original sample. Necessary because predicted original sample is clipped to [-1, 1] when + `self.config.clip_sample` is `True`. If no clipping has happened, "corrected" `model_output` would + coincide with the one provided as input and `use_clipped_model_output` will have not effect. + + Returns: + `torch.Tensor`: sample tensor at previous timestep. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + assert eta == 0.0 + + # See formulas (12) and (16) of DDIM paper https://huggingface.co/papers/2010.02502 + # Ideally, read DDIM paper in-detail understanding + + # Notation ( -> + # - pred_noise_t -> e_theta(x_t, t) + # - pred_original_sample -> f_theta(x_t, t) or x_0 + # - std_dev_t -> sigma_t + # - eta -> η + # - pred_sample_direction -> "direction pointing to x_t" + # - pred_prev_sample -> "x_t-1" + + # 1. get previous step value (=t-1) + t = timesteps + prev_t = t - self.config.num_train_timesteps // self.num_inference_steps + + t = t.view(-1, *([1] * (model_output.ndim - 1))) + prev_t = prev_t.view(-1, *([1] * (model_output.ndim - 1))) + + # 1. compute alphas, betas + self.alphas_cumprod = self.alphas_cumprod.to(model_output.device) + self.final_alpha_cumprod = self.final_alpha_cumprod.to(model_output.device) + alpha_prod_t = self.alphas_cumprod[t] + alpha_prod_t_prev = self.alphas_cumprod[torch.clip(prev_t, min=0)] + alpha_prod_t_prev[prev_t < 0] = torch.tensor(1.0) + + beta_prod_t = 1 - alpha_prod_t + + # 3. compute predicted original sample from predicted noise also called + # "predicted x_0" of formula (12) from https://huggingface.co/papers/2010.02502 + if self.config.prediction_type == "epsilon": + pred_original_sample = (sample - beta_prod_t ** (0.5) * model_output) / alpha_prod_t ** (0.5) + pred_epsilon = model_output + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + pred_epsilon = (sample - alpha_prod_t ** (0.5) * pred_original_sample) / beta_prod_t ** (0.5) + elif self.config.prediction_type == "v_prediction": + pred_original_sample = (alpha_prod_t**0.5) * sample - (beta_prod_t**0.5) * model_output + pred_epsilon = (alpha_prod_t**0.5) * model_output + (beta_prod_t**0.5) * sample + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, or" + " `v_prediction`" + ) + + # 4. Clip or threshold "predicted x_0" + if self.config.thresholding: + pred_original_sample = self._threshold_sample(pred_original_sample) + elif self.config.clip_sample: + pred_original_sample = pred_original_sample.clamp( + -self.config.clip_sample_range, self.config.clip_sample_range + ) + + # 5. compute variance: "sigma_t(η)" -> see formula (16) + # σ_t = sqrt((1 − α_t−1)/(1 − α_t)) * sqrt(1 − α_t/α_t−1) + variance = self._batch_get_variance(t, prev_t).to(model_output.device).view(*alpha_prod_t_prev.shape) + std_dev_t = eta * variance ** (0.5) + + if use_clipped_model_output: + # the pred_epsilon is always re-derived from the clipped x_0 in Glide + pred_epsilon = (sample - alpha_prod_t ** (0.5) * pred_original_sample) / beta_prod_t ** (0.5) + + # 6. compute "direction pointing to x_t" of formula (12) from https://huggingface.co/papers/2010.02502 + pred_sample_direction = (1 - alpha_prod_t_prev - std_dev_t**2) ** (0.5) * pred_epsilon + + # 7. compute x_t without "random noise" of formula (12) from https://huggingface.co/papers/2010.02502 + prev_sample = alpha_prod_t_prev ** (0.5) * pred_original_sample + pred_sample_direction + + return prev_sample + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as original_samples + # Move the self.alphas_cumprod to device to avoid redundant CPU to GPU data movement + # for the subsequent add_noise calls + self.alphas_cumprod = self.alphas_cumprod.to(device=original_samples.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=original_samples.dtype) + timesteps = timesteps.to(original_samples.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(original_samples.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(original_samples.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + noisy_samples = sqrt_alpha_prod * original_samples + sqrt_one_minus_alpha_prod * noise + return noisy_samples + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.get_velocity + def get_velocity(self, sample: torch.Tensor, noise: torch.Tensor, timesteps: torch.IntTensor) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as sample + self.alphas_cumprod = self.alphas_cumprod.to(device=sample.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=sample.dtype) + timesteps = timesteps.to(sample.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(sample.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(sample.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + velocity = sqrt_alpha_prod * noise - sqrt_one_minus_alpha_prod * sample + return velocity + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddpm.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddpm.py new file mode 100644 index 0000000000000000000000000000000000000000..4f99cf4ce57816bcdab6bd5f11e6af65293c50cc --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddpm.py @@ -0,0 +1,558 @@ +# Copyright 2024 UC Berkeley Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/ermongroup/ddim + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin + + +@dataclass +class DDPMSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +# Copied from diffusers.schedulers.scheduling_ddim.rescale_zero_terminal_snr +def rescale_zero_terminal_snr(betas): + """ + Rescales betas to have zero terminal SNR Based on https://huggingface.co/papers/2305.08891 (Algorithm 1) + + + Args: + betas (`torch.Tensor`): + the betas that the scheduler is being initialized with. + + Returns: + `torch.Tensor`: rescaled betas with zero terminal SNR + """ + # Convert betas to alphas_bar_sqrt + alphas = 1.0 - betas + alphas_cumprod = torch.cumprod(alphas, dim=0) + alphas_bar_sqrt = alphas_cumprod.sqrt() + + # Store old values. + alphas_bar_sqrt_0 = alphas_bar_sqrt[0].clone() + alphas_bar_sqrt_T = alphas_bar_sqrt[-1].clone() + + # Shift so the last timestep is zero. + alphas_bar_sqrt -= alphas_bar_sqrt_T + + # Scale so the first timestep is back to the old value. + alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T) + + # Convert alphas_bar_sqrt to betas + alphas_bar = alphas_bar_sqrt**2 # Revert sqrt + alphas = alphas_bar[1:] / alphas_bar[:-1] # Revert cumprod + alphas = torch.cat([alphas_bar[0:1], alphas]) + betas = 1 - alphas + + return betas + + +class DDPMScheduler(SchedulerMixin, ConfigMixin): + """ + `DDPMScheduler` explores the connections between denoising score matching and Langevin dynamics sampling. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, `squaredcos_cap_v2`, or `sigmoid`. + trained_betas (`np.ndarray`, *optional*): + An array of betas to pass directly to the constructor without using `beta_start` and `beta_end`. + variance_type (`str`, defaults to `"fixed_small"`): + Clip the variance when adding noise to the denoised sample. Choose from `fixed_small`, `fixed_small_log`, + `fixed_large`, `fixed_large_log`, `learned` or `learned_range`. + clip_sample (`bool`, defaults to `True`): + Clip the predicted sample for numerical stability. + clip_sample_range (`float`, defaults to 1.0): + The maximum magnitude for sample clipping. Valid only when `clip_sample=True`. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + thresholding (`bool`, defaults to `False`): + Whether to use the "dynamic thresholding" method. This is unsuitable for latent-space diffusion models such + as Stable Diffusion. + dynamic_thresholding_ratio (`float`, defaults to 0.995): + The ratio for the dynamic thresholding method. Valid only when `thresholding=True`. + sample_max_value (`float`, defaults to 1.0): + The threshold value for dynamic thresholding. Valid only when `thresholding=True`. + timestep_spacing (`str`, defaults to `"leading"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + rescale_betas_zero_snr (`bool`, defaults to `False`): + Whether to rescale the betas to have zero terminal SNR. This enables the model to generate very bright and + dark samples instead of limiting it to samples with medium brightness. Loosely related to + [`--offset_noise`](https://github.com/huggingface/diffusers/blob/74fd735eb073eb1d774b1ab4154a0876eb82f055/examples/dreambooth/train_dreambooth.py#L506). + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + variance_type: str = "fixed_small", + clip_sample: bool = True, + prediction_type: str = "epsilon", + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + clip_sample_range: float = 1.0, + sample_max_value: float = 1.0, + timestep_spacing: str = "leading", + steps_offset: int = 0, + rescale_betas_zero_snr: bool = False, + ): + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + elif beta_schedule == "sigmoid": + # GeoDiff sigmoid schedule + betas = torch.linspace(-6, 6, num_train_timesteps) + self.betas = torch.sigmoid(betas) * (beta_end - beta_start) + beta_start + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + # Rescale for zero SNR + if rescale_betas_zero_snr: + self.betas = rescale_zero_terminal_snr(self.betas) + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + self.one = torch.tensor(1.0) + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # setable values + self.custom_timesteps = False + self.num_inference_steps = None + self.timesteps = torch.from_numpy(np.arange(0, num_train_timesteps)[::-1].copy()) + + self.variance_type = variance_type + + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + def set_timesteps( + self, + num_inference_steps: Optional[int] = None, + device: Union[str, torch.device] = None, + timesteps: Optional[List[int]] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. If used, + `timesteps` must be `None`. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + timesteps (`List[int]`, *optional*): + Custom timesteps used to support arbitrary spacing between timesteps. If `None`, then the default + timestep spacing strategy of equal spacing between timesteps is used. If `timesteps` is passed, + `num_inference_steps` must be `None`. + + """ + if num_inference_steps is not None and timesteps is not None: + raise ValueError("Can only pass one of `num_inference_steps` or `custom_timesteps`.") + + if timesteps is not None: + for i in range(1, len(timesteps)): + if timesteps[i] >= timesteps[i - 1]: + raise ValueError("`custom_timesteps` must be in descending order.") + + if timesteps[0] >= self.config.num_train_timesteps: + raise ValueError( + f"`timesteps` must start before `self.config.train_timesteps`: {self.config.num_train_timesteps}." + ) + + timesteps = np.array(timesteps, dtype=np.int64) + self.custom_timesteps = True + else: + if num_inference_steps > self.config.num_train_timesteps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `self.config.train_timesteps`:" + f" {self.config.num_train_timesteps} as the unet model trained with this scheduler can only handle" + f" maximal {self.config.num_train_timesteps} timesteps." + ) + + self.num_inference_steps = num_inference_steps + self.custom_timesteps = False + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = ( + np.linspace(0, self.config.num_train_timesteps - 1, num_inference_steps) + .round()[::-1] + .copy() + .astype(np.int64) + ) + elif self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.int64) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = np.round(np.arange(self.config.num_train_timesteps, 0, -step_ratio)).astype(np.int64) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + self.timesteps = torch.from_numpy(timesteps).to(device) + + def _get_variance(self, t, predicted_variance=None, variance_type=None): + prev_t = self.previous_timestep(t) + + alpha_prod_t = self.alphas_cumprod[t] + alpha_prod_t_prev = self.alphas_cumprod[prev_t] if prev_t >= 0 else self.one + current_beta_t = 1 - alpha_prod_t / alpha_prod_t_prev + + # For t > 0, compute predicted variance βt (see formula (6) and (7) from https://huggingface.co/papers/2006.11239) + # and sample from it to get previous sample + # x_{t-1} ~ N(pred_prev_sample, variance) == add variance to pred_sample + variance = (1 - alpha_prod_t_prev) / (1 - alpha_prod_t) * current_beta_t + + # we always take the log of variance, so clamp it to ensure it's not 0 + variance = torch.clamp(variance, min=1e-20) + + if variance_type is None: + variance_type = self.config.variance_type + + # hacks - were probably added for training stability + if variance_type == "fixed_small": + variance = variance + # for rl-diffuser https://huggingface.co/papers/2205.09991 + elif variance_type == "fixed_small_log": + variance = torch.log(variance) + variance = torch.exp(0.5 * variance) + elif variance_type == "fixed_large": + variance = current_beta_t + elif variance_type == "fixed_large_log": + # Glide max_log + variance = torch.log(current_beta_t) + elif variance_type == "learned": + return predicted_variance + elif variance_type == "learned_range": + min_log = torch.log(variance) + max_log = torch.log(current_beta_t) + frac = (predicted_variance + 1) / 2 + variance = frac * max_log + (1 - frac) * min_log + + return variance + + def _threshold_sample(self, sample: torch.Tensor) -> torch.Tensor: + """ + "Dynamic thresholding: At each sampling step we set s to a certain percentile absolute pixel value in xt0 (the + prediction of x_0 at timestep t), and if s > 1, then we threshold xt0 to the range [-s, s] and then divide by + s. Dynamic thresholding pushes saturated pixels (those near -1 and 1) inwards, thereby actively preventing + pixels from saturation at each step. We find that dynamic thresholding results in significantly better + photorealism as well as better image-text alignment, especially when using very large guidance weights." + + https://huggingface.co/papers/2205.11487 + """ + dtype = sample.dtype + batch_size, channels, *remaining_dims = sample.shape + + if dtype not in (torch.float32, torch.float64): + sample = sample.float() # upcast for quantile calculation, and clamp not implemented for cpu half + + # Flatten sample for doing quantile calculation along each image + sample = sample.reshape(batch_size, channels * np.prod(remaining_dims)) + + abs_sample = sample.abs() # "a certain percentile absolute pixel value" + + s = torch.quantile(abs_sample, self.config.dynamic_thresholding_ratio, dim=1) + s = torch.clamp( + s, min=1, max=self.config.sample_max_value + ) # When clamped to min=1, equivalent to standard clipping to [-1, 1] + s = s.unsqueeze(1) # (batch_size, 1) because clamp will broadcast along dim=0 + sample = torch.clamp(sample, -s, s) / s # "we threshold xt0 to the range [-s, s] and then divide by s" + + sample = sample.reshape(batch_size, channels, *remaining_dims) + sample = sample.to(dtype) + + return sample + + def step( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + generator=None, + return_dict: bool = True, + ) -> Union[DDPMSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_ddpm.DDPMSchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_ddpm.DDPMSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_ddpm.DDPMSchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + t = timestep + + prev_t = self.previous_timestep(t) + + if model_output.shape[1] == sample.shape[1] * 2 and self.variance_type in ["learned", "learned_range"]: + model_output, predicted_variance = torch.split(model_output, sample.shape[1], dim=1) + else: + predicted_variance = None + + # 1. compute alphas, betas + alpha_prod_t = self.alphas_cumprod[t] + alpha_prod_t_prev = self.alphas_cumprod[prev_t] if prev_t >= 0 else self.one + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + current_alpha_t = alpha_prod_t / alpha_prod_t_prev + current_beta_t = 1 - current_alpha_t + + # 2. compute predicted original sample from predicted noise also called + # "predicted x_0" of formula (15) from https://huggingface.co/papers/2006.11239 + if self.config.prediction_type == "epsilon": + pred_original_sample = (sample - beta_prod_t ** (0.5) * model_output) / alpha_prod_t ** (0.5) + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + elif self.config.prediction_type == "v_prediction": + pred_original_sample = (alpha_prod_t**0.5) * sample - (beta_prod_t**0.5) * model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample` or" + " `v_prediction` for the DDPMScheduler." + ) + + # 3. Clip or threshold "predicted x_0" + if self.config.thresholding: + pred_original_sample = self._threshold_sample(pred_original_sample) + elif self.config.clip_sample: + pred_original_sample = pred_original_sample.clamp( + -self.config.clip_sample_range, self.config.clip_sample_range + ) + + # 4. Compute coefficients for pred_original_sample x_0 and current sample x_t + # See formula (7) from https://huggingface.co/papers/2006.11239 + pred_original_sample_coeff = (alpha_prod_t_prev ** (0.5) * current_beta_t) / beta_prod_t + current_sample_coeff = current_alpha_t ** (0.5) * beta_prod_t_prev / beta_prod_t + + # 5. Compute predicted previous sample µ_t + # See formula (7) from https://huggingface.co/papers/2006.11239 + pred_prev_sample = pred_original_sample_coeff * pred_original_sample + current_sample_coeff * sample + + # 6. Add noise + variance = 0 + if t > 0: + device = model_output.device + variance_noise = randn_tensor( + model_output.shape, generator=generator, device=device, dtype=model_output.dtype + ) + if self.variance_type == "fixed_small_log": + variance = self._get_variance(t, predicted_variance=predicted_variance) * variance_noise + elif self.variance_type == "learned_range": + variance = self._get_variance(t, predicted_variance=predicted_variance) + variance = torch.exp(0.5 * variance) * variance_noise + else: + variance = (self._get_variance(t, predicted_variance=predicted_variance) ** 0.5) * variance_noise + + pred_prev_sample = pred_prev_sample + variance + + if not return_dict: + return ( + pred_prev_sample, + pred_original_sample, + ) + + return DDPMSchedulerOutput(prev_sample=pred_prev_sample, pred_original_sample=pred_original_sample) + + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as original_samples + # Move the self.alphas_cumprod to device to avoid redundant CPU to GPU data movement + # for the subsequent add_noise calls + self.alphas_cumprod = self.alphas_cumprod.to(device=original_samples.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=original_samples.dtype) + timesteps = timesteps.to(original_samples.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(original_samples.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(original_samples.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + noisy_samples = sqrt_alpha_prod * original_samples + sqrt_one_minus_alpha_prod * noise + return noisy_samples + + def get_velocity(self, sample: torch.Tensor, noise: torch.Tensor, timesteps: torch.IntTensor) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as sample + self.alphas_cumprod = self.alphas_cumprod.to(device=sample.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=sample.dtype) + timesteps = timesteps.to(sample.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(sample.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(sample.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + velocity = sqrt_alpha_prod * noise - sqrt_one_minus_alpha_prod * sample + return velocity + + def __len__(self): + return self.config.num_train_timesteps + + def previous_timestep(self, timestep): + if self.custom_timesteps or self.num_inference_steps: + index = (self.timesteps == timestep).nonzero(as_tuple=True)[0][0] + if index == self.timesteps.shape[0] - 1: + prev_t = torch.tensor(-1) + else: + prev_t = self.timesteps[index + 1] + else: + prev_t = timestep - 1 + return prev_t diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddpm_flax.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddpm_flax.py new file mode 100644 index 0000000000000000000000000000000000000000..a81ad4168d99678dc6f3b0e155acc402863324fe --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddpm_flax.py @@ -0,0 +1,303 @@ +# Copyright 2024 UC Berkeley Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/ermongroup/ddim + +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import flax +import jax +import jax.numpy as jnp + +from ..configuration_utils import ConfigMixin, register_to_config +from .scheduling_utils_flax import ( + CommonSchedulerState, + FlaxKarrasDiffusionSchedulers, + FlaxSchedulerMixin, + FlaxSchedulerOutput, + add_noise_common, + get_velocity_common, +) + + +@flax.struct.dataclass +class DDPMSchedulerState: + common: CommonSchedulerState + + # setable values + init_noise_sigma: jnp.ndarray + timesteps: jnp.ndarray + num_inference_steps: Optional[int] = None + + @classmethod + def create(cls, common: CommonSchedulerState, init_noise_sigma: jnp.ndarray, timesteps: jnp.ndarray): + return cls(common=common, init_noise_sigma=init_noise_sigma, timesteps=timesteps) + + +@dataclass +class FlaxDDPMSchedulerOutput(FlaxSchedulerOutput): + state: DDPMSchedulerState + + +class FlaxDDPMScheduler(FlaxSchedulerMixin, ConfigMixin): + """ + Denoising diffusion probabilistic models (DDPMs) explores the connections between denoising score matching and + Langevin dynamics sampling. + + [`~ConfigMixin`] takes care of storing all config attributes that are passed in the scheduler's `__init__` + function, such as `num_train_timesteps`. They can be accessed via `scheduler.config.num_train_timesteps`. + [`SchedulerMixin`] provides general loading and saving functionality via the [`SchedulerMixin.save_pretrained`] and + [`~SchedulerMixin.from_pretrained`] functions. + + For more details, see the original paper: https://huggingface.co/papers/2006.11239 + + Args: + num_train_timesteps (`int`): number of diffusion steps used to train the model. + beta_start (`float`): the starting `beta` value of inference. + beta_end (`float`): the final `beta` value. + beta_schedule (`str`): + the beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, optional): + option to pass an array of betas directly to the constructor to bypass `beta_start`, `beta_end` etc. + variance_type (`str`): + options to clip the variance used when adding noise to the denoised sample. Choose from `fixed_small`, + `fixed_small_log`, `fixed_large`, `fixed_large_log`, `learned` or `learned_range`. + clip_sample (`bool`, default `True`): + option to clip predicted sample between -1 and 1 for numerical stability. + prediction_type (`str`, default `epsilon`): + indicates whether the model predicts the noise (epsilon), or the samples. One of `epsilon`, `sample`. + `v-prediction` is not supported for this scheduler. + dtype (`jnp.dtype`, *optional*, defaults to `jnp.float32`): + the `dtype` used for params and computation. + """ + + _compatibles = [e.name for e in FlaxKarrasDiffusionSchedulers] + + dtype: jnp.dtype + + @property + def has_state(self): + return True + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[jnp.ndarray] = None, + variance_type: str = "fixed_small", + clip_sample: bool = True, + prediction_type: str = "epsilon", + dtype: jnp.dtype = jnp.float32, + ): + self.dtype = dtype + + def create_state(self, common: Optional[CommonSchedulerState] = None) -> DDPMSchedulerState: + if common is None: + common = CommonSchedulerState.create(self) + + # standard deviation of the initial noise distribution + init_noise_sigma = jnp.array(1.0, dtype=self.dtype) + + timesteps = jnp.arange(0, self.config.num_train_timesteps).round()[::-1] + + return DDPMSchedulerState.create( + common=common, + init_noise_sigma=init_noise_sigma, + timesteps=timesteps, + ) + + def scale_model_input( + self, state: DDPMSchedulerState, sample: jnp.ndarray, timestep: Optional[int] = None + ) -> jnp.ndarray: + """ + Args: + state (`PNDMSchedulerState`): the `FlaxPNDMScheduler` state data class instance. + sample (`jnp.ndarray`): input sample + timestep (`int`, optional): current timestep + + Returns: + `jnp.ndarray`: scaled input sample + """ + return sample + + def set_timesteps( + self, state: DDPMSchedulerState, num_inference_steps: int, shape: Tuple = () + ) -> DDPMSchedulerState: + """ + Sets the discrete timesteps used for the diffusion chain. Supporting function to be run before inference. + + Args: + state (`DDIMSchedulerState`): + the `FlaxDDPMScheduler` state data class instance. + num_inference_steps (`int`): + the number of diffusion steps used when generating samples with a pre-trained model. + """ + + step_ratio = self.config.num_train_timesteps // num_inference_steps + # creates integer timesteps by multiplying by ratio + # rounding to avoid issues when num_inference_step is power of 3 + timesteps = (jnp.arange(0, num_inference_steps) * step_ratio).round()[::-1] + + return state.replace( + num_inference_steps=num_inference_steps, + timesteps=timesteps, + ) + + def _get_variance(self, state: DDPMSchedulerState, t, predicted_variance=None, variance_type=None): + alpha_prod_t = state.common.alphas_cumprod[t] + alpha_prod_t_prev = jnp.where(t > 0, state.common.alphas_cumprod[t - 1], jnp.array(1.0, dtype=self.dtype)) + + # For t > 0, compute predicted variance βt (see formula (6) and (7) from https://huggingface.co/papers/2006.11239) + # and sample from it to get previous sample + # x_{t-1} ~ N(pred_prev_sample, variance) == add variance to pred_sample + variance = (1 - alpha_prod_t_prev) / (1 - alpha_prod_t) * state.common.betas[t] + + if variance_type is None: + variance_type = self.config.variance_type + + # hacks - were probably added for training stability + if variance_type == "fixed_small": + variance = jnp.clip(variance, a_min=1e-20) + # for rl-diffuser https://huggingface.co/papers/2205.09991 + elif variance_type == "fixed_small_log": + variance = jnp.log(jnp.clip(variance, a_min=1e-20)) + elif variance_type == "fixed_large": + variance = state.common.betas[t] + elif variance_type == "fixed_large_log": + # Glide max_log + variance = jnp.log(state.common.betas[t]) + elif variance_type == "learned": + return predicted_variance + elif variance_type == "learned_range": + min_log = variance + max_log = state.common.betas[t] + frac = (predicted_variance + 1) / 2 + variance = frac * max_log + (1 - frac) * min_log + + return variance + + def step( + self, + state: DDPMSchedulerState, + model_output: jnp.ndarray, + timestep: int, + sample: jnp.ndarray, + key: Optional[jax.Array] = None, + return_dict: bool = True, + ) -> Union[FlaxDDPMSchedulerOutput, Tuple]: + """ + Predict the sample at the previous timestep by reversing the SDE. Core function to propagate the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + state (`DDPMSchedulerState`): the `FlaxDDPMScheduler` state data class instance. + model_output (`jnp.ndarray`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + key (`jax.Array`): a PRNG key. + return_dict (`bool`): option for returning tuple rather than FlaxDDPMSchedulerOutput class + + Returns: + [`FlaxDDPMSchedulerOutput`] or `tuple`: [`FlaxDDPMSchedulerOutput`] if `return_dict` is True, otherwise a + `tuple`. When returning a tuple, the first element is the sample tensor. + + """ + t = timestep + + if key is None: + key = jax.random.key(0) + + if ( + len(model_output.shape) > 1 + and model_output.shape[1] == sample.shape[1] * 2 + and self.config.variance_type in ["learned", "learned_range"] + ): + model_output, predicted_variance = jnp.split(model_output, sample.shape[1], axis=1) + else: + predicted_variance = None + + # 1. compute alphas, betas + alpha_prod_t = state.common.alphas_cumprod[t] + alpha_prod_t_prev = jnp.where(t > 0, state.common.alphas_cumprod[t - 1], jnp.array(1.0, dtype=self.dtype)) + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + # 2. compute predicted original sample from predicted noise also called + # "predicted x_0" of formula (15) from https://huggingface.co/papers/2006.11239 + if self.config.prediction_type == "epsilon": + pred_original_sample = (sample - beta_prod_t ** (0.5) * model_output) / alpha_prod_t ** (0.5) + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + elif self.config.prediction_type == "v_prediction": + pred_original_sample = (alpha_prod_t**0.5) * sample - (beta_prod_t**0.5) * model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample` " + " for the FlaxDDPMScheduler." + ) + + # 3. Clip "predicted x_0" + if self.config.clip_sample: + pred_original_sample = jnp.clip(pred_original_sample, -1, 1) + + # 4. Compute coefficients for pred_original_sample x_0 and current sample x_t + # See formula (7) from https://huggingface.co/papers/2006.11239 + pred_original_sample_coeff = (alpha_prod_t_prev ** (0.5) * state.common.betas[t]) / beta_prod_t + current_sample_coeff = state.common.alphas[t] ** (0.5) * beta_prod_t_prev / beta_prod_t + + # 5. Compute predicted previous sample µ_t + # See formula (7) from https://huggingface.co/papers/2006.11239 + pred_prev_sample = pred_original_sample_coeff * pred_original_sample + current_sample_coeff * sample + + # 6. Add noise + def random_variance(): + split_key = jax.random.split(key, num=1)[0] + noise = jax.random.normal(split_key, shape=model_output.shape, dtype=self.dtype) + return (self._get_variance(state, t, predicted_variance=predicted_variance) ** 0.5) * noise + + variance = jnp.where(t > 0, random_variance(), jnp.zeros(model_output.shape, dtype=self.dtype)) + + pred_prev_sample = pred_prev_sample + variance + + if not return_dict: + return (pred_prev_sample, state) + + return FlaxDDPMSchedulerOutput(prev_sample=pred_prev_sample, state=state) + + def add_noise( + self, + state: DDPMSchedulerState, + original_samples: jnp.ndarray, + noise: jnp.ndarray, + timesteps: jnp.ndarray, + ) -> jnp.ndarray: + return add_noise_common(state.common, original_samples, noise, timesteps) + + def get_velocity( + self, + state: DDPMSchedulerState, + sample: jnp.ndarray, + noise: jnp.ndarray, + timesteps: jnp.ndarray, + ) -> jnp.ndarray: + return get_velocity_common(state.common, sample, noise, timesteps) + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddpm_parallel.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddpm_parallel.py new file mode 100644 index 0000000000000000000000000000000000000000..cc5d55c0b62189a0c953b0941772eb812213294d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddpm_parallel.py @@ -0,0 +1,649 @@ +# Copyright 2024 ParaDiGMS authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/ermongroup/ddim + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput +class DDPMParallelSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +# Copied from diffusers.schedulers.scheduling_ddim.rescale_zero_terminal_snr +def rescale_zero_terminal_snr(betas): + """ + Rescales betas to have zero terminal SNR Based on https://huggingface.co/papers/2305.08891 (Algorithm 1) + + + Args: + betas (`torch.Tensor`): + the betas that the scheduler is being initialized with. + + Returns: + `torch.Tensor`: rescaled betas with zero terminal SNR + """ + # Convert betas to alphas_bar_sqrt + alphas = 1.0 - betas + alphas_cumprod = torch.cumprod(alphas, dim=0) + alphas_bar_sqrt = alphas_cumprod.sqrt() + + # Store old values. + alphas_bar_sqrt_0 = alphas_bar_sqrt[0].clone() + alphas_bar_sqrt_T = alphas_bar_sqrt[-1].clone() + + # Shift so the last timestep is zero. + alphas_bar_sqrt -= alphas_bar_sqrt_T + + # Scale so the first timestep is back to the old value. + alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T) + + # Convert alphas_bar_sqrt to betas + alphas_bar = alphas_bar_sqrt**2 # Revert sqrt + alphas = alphas_bar[1:] / alphas_bar[:-1] # Revert cumprod + alphas = torch.cat([alphas_bar[0:1], alphas]) + betas = 1 - alphas + + return betas + + +class DDPMParallelScheduler(SchedulerMixin, ConfigMixin): + """ + Denoising diffusion probabilistic models (DDPMs) explores the connections between denoising score matching and + Langevin dynamics sampling. + + [`~ConfigMixin`] takes care of storing all config attributes that are passed in the scheduler's `__init__` + function, such as `num_train_timesteps`. They can be accessed via `scheduler.config.num_train_timesteps`. + [`SchedulerMixin`] provides general loading and saving functionality via the [`SchedulerMixin.save_pretrained`] and + [`~SchedulerMixin.from_pretrained`] functions. + + For more details, see the original paper: https://huggingface.co/papers/2006.11239 + + Args: + num_train_timesteps (`int`): number of diffusion steps used to train the model. + beta_start (`float`): the starting `beta` value of inference. + beta_end (`float`): the final `beta` value. + beta_schedule (`str`): + the beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, `squaredcos_cap_v2` or `sigmoid`. + trained_betas (`np.ndarray`, optional): + option to pass an array of betas directly to the constructor to bypass `beta_start`, `beta_end` etc. + variance_type (`str`): + options to clip the variance used when adding noise to the denoised sample. Choose from `fixed_small`, + `fixed_small_log`, `fixed_large`, `fixed_large_log`, `learned` or `learned_range`. + clip_sample (`bool`, default `True`): + option to clip predicted sample for numerical stability. + clip_sample_range (`float`, default `1.0`): + the maximum magnitude for sample clipping. Valid only when `clip_sample=True`. + prediction_type (`str`, default `epsilon`, optional): + prediction type of the scheduler function, one of `epsilon` (predicting the noise of the diffusion + process), `sample` (directly predicting the noisy sample`) or `v_prediction` (see section 2.4 + https://imagen.research.google/video/paper.pdf) + thresholding (`bool`, default `False`): + whether to use the "dynamic thresholding" method (introduced by Imagen, + https://huggingface.co/papers/2205.11487). Note that the thresholding method is unsuitable for latent-space + diffusion models (such as stable-diffusion). + dynamic_thresholding_ratio (`float`, default `0.995`): + the ratio for the dynamic thresholding method. Default is `0.995`, the same as Imagen + (https://huggingface.co/papers/2205.11487). Valid only when `thresholding=True`. + sample_max_value (`float`, default `1.0`): + the threshold value for dynamic thresholding. Valid only when `thresholding=True`. + timestep_spacing (`str`, default `"leading"`): + The way the timesteps should be scaled. Refer to Table 2. of [Common Diffusion Noise Schedules and Sample + Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, default `0`): + An offset added to the inference steps, as required by some model families. + rescale_betas_zero_snr (`bool`, defaults to `False`): + Whether to rescale the betas to have zero terminal SNR. This enables the model to generate very bright and + dark samples instead of limiting it to samples with medium brightness. Loosely related to + [`--offset_noise`](https://github.com/huggingface/diffusers/blob/74fd735eb073eb1d774b1ab4154a0876eb82f055/examples/dreambooth/train_dreambooth.py#L506). + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + _is_ode_scheduler = False + + @register_to_config + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.__init__ + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + variance_type: str = "fixed_small", + clip_sample: bool = True, + prediction_type: str = "epsilon", + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + clip_sample_range: float = 1.0, + sample_max_value: float = 1.0, + timestep_spacing: str = "leading", + steps_offset: int = 0, + rescale_betas_zero_snr: bool = False, + ): + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + elif beta_schedule == "sigmoid": + # GeoDiff sigmoid schedule + betas = torch.linspace(-6, 6, num_train_timesteps) + self.betas = torch.sigmoid(betas) * (beta_end - beta_start) + beta_start + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + # Rescale for zero SNR + if rescale_betas_zero_snr: + self.betas = rescale_zero_terminal_snr(self.betas) + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + self.one = torch.tensor(1.0) + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # setable values + self.custom_timesteps = False + self.num_inference_steps = None + self.timesteps = torch.from_numpy(np.arange(0, num_train_timesteps)[::-1].copy()) + + self.variance_type = variance_type + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.scale_model_input + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.set_timesteps + def set_timesteps( + self, + num_inference_steps: Optional[int] = None, + device: Union[str, torch.device] = None, + timesteps: Optional[List[int]] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. If used, + `timesteps` must be `None`. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + timesteps (`List[int]`, *optional*): + Custom timesteps used to support arbitrary spacing between timesteps. If `None`, then the default + timestep spacing strategy of equal spacing between timesteps is used. If `timesteps` is passed, + `num_inference_steps` must be `None`. + + """ + if num_inference_steps is not None and timesteps is not None: + raise ValueError("Can only pass one of `num_inference_steps` or `custom_timesteps`.") + + if timesteps is not None: + for i in range(1, len(timesteps)): + if timesteps[i] >= timesteps[i - 1]: + raise ValueError("`custom_timesteps` must be in descending order.") + + if timesteps[0] >= self.config.num_train_timesteps: + raise ValueError( + f"`timesteps` must start before `self.config.train_timesteps`: {self.config.num_train_timesteps}." + ) + + timesteps = np.array(timesteps, dtype=np.int64) + self.custom_timesteps = True + else: + if num_inference_steps > self.config.num_train_timesteps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `self.config.train_timesteps`:" + f" {self.config.num_train_timesteps} as the unet model trained with this scheduler can only handle" + f" maximal {self.config.num_train_timesteps} timesteps." + ) + + self.num_inference_steps = num_inference_steps + self.custom_timesteps = False + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = ( + np.linspace(0, self.config.num_train_timesteps - 1, num_inference_steps) + .round()[::-1] + .copy() + .astype(np.int64) + ) + elif self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.int64) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = np.round(np.arange(self.config.num_train_timesteps, 0, -step_ratio)).astype(np.int64) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + self.timesteps = torch.from_numpy(timesteps).to(device) + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler._get_variance + def _get_variance(self, t, predicted_variance=None, variance_type=None): + prev_t = self.previous_timestep(t) + + alpha_prod_t = self.alphas_cumprod[t] + alpha_prod_t_prev = self.alphas_cumprod[prev_t] if prev_t >= 0 else self.one + current_beta_t = 1 - alpha_prod_t / alpha_prod_t_prev + + # For t > 0, compute predicted variance βt (see formula (6) and (7) from https://huggingface.co/papers/2006.11239) + # and sample from it to get previous sample + # x_{t-1} ~ N(pred_prev_sample, variance) == add variance to pred_sample + variance = (1 - alpha_prod_t_prev) / (1 - alpha_prod_t) * current_beta_t + + # we always take the log of variance, so clamp it to ensure it's not 0 + variance = torch.clamp(variance, min=1e-20) + + if variance_type is None: + variance_type = self.config.variance_type + + # hacks - were probably added for training stability + if variance_type == "fixed_small": + variance = variance + # for rl-diffuser https://huggingface.co/papers/2205.09991 + elif variance_type == "fixed_small_log": + variance = torch.log(variance) + variance = torch.exp(0.5 * variance) + elif variance_type == "fixed_large": + variance = current_beta_t + elif variance_type == "fixed_large_log": + # Glide max_log + variance = torch.log(current_beta_t) + elif variance_type == "learned": + return predicted_variance + elif variance_type == "learned_range": + min_log = torch.log(variance) + max_log = torch.log(current_beta_t) + frac = (predicted_variance + 1) / 2 + variance = frac * max_log + (1 - frac) * min_log + + return variance + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler._threshold_sample + def _threshold_sample(self, sample: torch.Tensor) -> torch.Tensor: + """ + "Dynamic thresholding: At each sampling step we set s to a certain percentile absolute pixel value in xt0 (the + prediction of x_0 at timestep t), and if s > 1, then we threshold xt0 to the range [-s, s] and then divide by + s. Dynamic thresholding pushes saturated pixels (those near -1 and 1) inwards, thereby actively preventing + pixels from saturation at each step. We find that dynamic thresholding results in significantly better + photorealism as well as better image-text alignment, especially when using very large guidance weights." + + https://huggingface.co/papers/2205.11487 + """ + dtype = sample.dtype + batch_size, channels, *remaining_dims = sample.shape + + if dtype not in (torch.float32, torch.float64): + sample = sample.float() # upcast for quantile calculation, and clamp not implemented for cpu half + + # Flatten sample for doing quantile calculation along each image + sample = sample.reshape(batch_size, channels * np.prod(remaining_dims)) + + abs_sample = sample.abs() # "a certain percentile absolute pixel value" + + s = torch.quantile(abs_sample, self.config.dynamic_thresholding_ratio, dim=1) + s = torch.clamp( + s, min=1, max=self.config.sample_max_value + ) # When clamped to min=1, equivalent to standard clipping to [-1, 1] + s = s.unsqueeze(1) # (batch_size, 1) because clamp will broadcast along dim=0 + sample = torch.clamp(sample, -s, s) / s # "we threshold xt0 to the range [-s, s] and then divide by s" + + sample = sample.reshape(batch_size, channels, *remaining_dims) + sample = sample.to(dtype) + + return sample + + def step( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + generator=None, + return_dict: bool = True, + ) -> Union[DDPMParallelSchedulerOutput, Tuple]: + """ + Predict the sample at the previous timestep by reversing the SDE. Core function to propagate the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + current instance of sample being created by diffusion process. + generator: random number generator. + return_dict (`bool`): option for returning tuple rather than DDPMParallelSchedulerOutput class + + Returns: + [`~schedulers.scheduling_utils.DDPMParallelSchedulerOutput`] or `tuple`: + [`~schedulers.scheduling_utils.DDPMParallelSchedulerOutput`] if `return_dict` is True, otherwise a `tuple`. + When returning a tuple, the first element is the sample tensor. + + """ + t = timestep + + prev_t = self.previous_timestep(t) + + if model_output.shape[1] == sample.shape[1] * 2 and self.variance_type in ["learned", "learned_range"]: + model_output, predicted_variance = torch.split(model_output, sample.shape[1], dim=1) + else: + predicted_variance = None + + # 1. compute alphas, betas + alpha_prod_t = self.alphas_cumprod[t] + alpha_prod_t_prev = self.alphas_cumprod[prev_t] if prev_t >= 0 else self.one + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + current_alpha_t = alpha_prod_t / alpha_prod_t_prev + current_beta_t = 1 - current_alpha_t + + # 2. compute predicted original sample from predicted noise also called + # "predicted x_0" of formula (15) from https://huggingface.co/papers/2006.11239 + if self.config.prediction_type == "epsilon": + pred_original_sample = (sample - beta_prod_t ** (0.5) * model_output) / alpha_prod_t ** (0.5) + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + elif self.config.prediction_type == "v_prediction": + pred_original_sample = (alpha_prod_t**0.5) * sample - (beta_prod_t**0.5) * model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample` or" + " `v_prediction` for the DDPMScheduler." + ) + + # 3. Clip or threshold "predicted x_0" + if self.config.thresholding: + pred_original_sample = self._threshold_sample(pred_original_sample) + elif self.config.clip_sample: + pred_original_sample = pred_original_sample.clamp( + -self.config.clip_sample_range, self.config.clip_sample_range + ) + + # 4. Compute coefficients for pred_original_sample x_0 and current sample x_t + # See formula (7) from https://huggingface.co/papers/2006.11239 + pred_original_sample_coeff = (alpha_prod_t_prev ** (0.5) * current_beta_t) / beta_prod_t + current_sample_coeff = current_alpha_t ** (0.5) * beta_prod_t_prev / beta_prod_t + + # 5. Compute predicted previous sample µ_t + # See formula (7) from https://huggingface.co/papers/2006.11239 + pred_prev_sample = pred_original_sample_coeff * pred_original_sample + current_sample_coeff * sample + + # 6. Add noise + variance = 0 + if t > 0: + device = model_output.device + variance_noise = randn_tensor( + model_output.shape, generator=generator, device=device, dtype=model_output.dtype + ) + if self.variance_type == "fixed_small_log": + variance = self._get_variance(t, predicted_variance=predicted_variance) * variance_noise + elif self.variance_type == "learned_range": + variance = self._get_variance(t, predicted_variance=predicted_variance) + variance = torch.exp(0.5 * variance) * variance_noise + else: + variance = (self._get_variance(t, predicted_variance=predicted_variance) ** 0.5) * variance_noise + + pred_prev_sample = pred_prev_sample + variance + + if not return_dict: + return ( + pred_prev_sample, + pred_original_sample, + ) + + return DDPMParallelSchedulerOutput(prev_sample=pred_prev_sample, pred_original_sample=pred_original_sample) + + def batch_step_no_noise( + self, + model_output: torch.Tensor, + timesteps: List[int], + sample: torch.Tensor, + ) -> torch.Tensor: + """ + Batched version of the `step` function, to be able to reverse the SDE for multiple samples/timesteps at once. + Also, does not add any noise to the predicted sample, which is necessary for parallel sampling where the noise + is pre-sampled by the pipeline. + + Predict the sample at the previous timestep by reversing the SDE. Core function to propagate the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): direct output from learned diffusion model. + timesteps (`List[int]`): + current discrete timesteps in the diffusion chain. This is now a list of integers. + sample (`torch.Tensor`): + current instance of sample being created by diffusion process. + + Returns: + `torch.Tensor`: sample tensor at previous timestep. + """ + t = timesteps + num_inference_steps = self.num_inference_steps if self.num_inference_steps else self.config.num_train_timesteps + prev_t = t - self.config.num_train_timesteps // num_inference_steps + + t = t.view(-1, *([1] * (model_output.ndim - 1))) + prev_t = prev_t.view(-1, *([1] * (model_output.ndim - 1))) + + if model_output.shape[1] == sample.shape[1] * 2 and self.variance_type in ["learned", "learned_range"]: + model_output, predicted_variance = torch.split(model_output, sample.shape[1], dim=1) + else: + pass + + # 1. compute alphas, betas + self.alphas_cumprod = self.alphas_cumprod.to(model_output.device) + alpha_prod_t = self.alphas_cumprod[t] + alpha_prod_t_prev = self.alphas_cumprod[torch.clip(prev_t, min=0)] + alpha_prod_t_prev[prev_t < 0] = torch.tensor(1.0) + + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + current_alpha_t = alpha_prod_t / alpha_prod_t_prev + current_beta_t = 1 - current_alpha_t + + # 2. compute predicted original sample from predicted noise also called + # "predicted x_0" of formula (15) from https://huggingface.co/papers/2006.11239 + if self.config.prediction_type == "epsilon": + pred_original_sample = (sample - beta_prod_t ** (0.5) * model_output) / alpha_prod_t ** (0.5) + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + elif self.config.prediction_type == "v_prediction": + pred_original_sample = (alpha_prod_t**0.5) * sample - (beta_prod_t**0.5) * model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample` or" + " `v_prediction` for the DDPMParallelScheduler." + ) + + # 3. Clip or threshold "predicted x_0" + if self.config.thresholding: + pred_original_sample = self._threshold_sample(pred_original_sample) + elif self.config.clip_sample: + pred_original_sample = pred_original_sample.clamp( + -self.config.clip_sample_range, self.config.clip_sample_range + ) + + # 4. Compute coefficients for pred_original_sample x_0 and current sample x_t + # See formula (7) from https://huggingface.co/papers/2006.11239 + pred_original_sample_coeff = (alpha_prod_t_prev ** (0.5) * current_beta_t) / beta_prod_t + current_sample_coeff = current_alpha_t ** (0.5) * beta_prod_t_prev / beta_prod_t + + # 5. Compute predicted previous sample µ_t + # See formula (7) from https://huggingface.co/papers/2006.11239 + pred_prev_sample = pred_original_sample_coeff * pred_original_sample + current_sample_coeff * sample + + return pred_prev_sample + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as original_samples + # Move the self.alphas_cumprod to device to avoid redundant CPU to GPU data movement + # for the subsequent add_noise calls + self.alphas_cumprod = self.alphas_cumprod.to(device=original_samples.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=original_samples.dtype) + timesteps = timesteps.to(original_samples.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(original_samples.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(original_samples.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + noisy_samples = sqrt_alpha_prod * original_samples + sqrt_one_minus_alpha_prod * noise + return noisy_samples + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.get_velocity + def get_velocity(self, sample: torch.Tensor, noise: torch.Tensor, timesteps: torch.IntTensor) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as sample + self.alphas_cumprod = self.alphas_cumprod.to(device=sample.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=sample.dtype) + timesteps = timesteps.to(sample.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(sample.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(sample.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + velocity = sqrt_alpha_prod * noise - sqrt_one_minus_alpha_prod * sample + return velocity + + def __len__(self): + return self.config.num_train_timesteps + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.previous_timestep + def previous_timestep(self, timestep): + if self.custom_timesteps or self.num_inference_steps: + index = (self.timesteps == timestep).nonzero(as_tuple=True)[0][0] + if index == self.timesteps.shape[0] - 1: + prev_t = torch.tensor(-1) + else: + prev_t = self.timesteps[index + 1] + else: + prev_t = timestep - 1 + return prev_t diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddpm_wuerstchen.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddpm_wuerstchen.py new file mode 100644 index 0000000000000000000000000000000000000000..a7f607c5eff0d7bc6e1c2333d147e5b6a69d9831 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ddpm_wuerstchen.py @@ -0,0 +1,230 @@ +# Copyright (c) 2022 Pablo Pernías MIT License +# Copyright 2024 UC Berkeley Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/ermongroup/ddim + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import SchedulerMixin + + +@dataclass +class DDPMWuerstchenSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's step function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample (x_{t-1}) of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + """ + + prev_sample: torch.Tensor + + +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +class DDPMWuerstchenScheduler(SchedulerMixin, ConfigMixin): + """ + Denoising diffusion probabilistic models (DDPMs) explores the connections between denoising score matching and + Langevin dynamics sampling. + + [`~ConfigMixin`] takes care of storing all config attributes that are passed in the scheduler's `__init__` + function, such as `num_train_timesteps`. They can be accessed via `scheduler.config.num_train_timesteps`. + [`SchedulerMixin`] provides general loading and saving functionality via the [`SchedulerMixin.save_pretrained`] and + [`~SchedulerMixin.from_pretrained`] functions. + + For more details, see the original paper: https://huggingface.co/papers/2006.11239 + + Args: + scaler (`float`): .... + s (`float`): .... + """ + + @register_to_config + def __init__( + self, + scaler: float = 1.0, + s: float = 0.008, + ): + self.scaler = scaler + self.s = torch.tensor([s]) + self._init_alpha_cumprod = torch.cos(self.s / (1 + self.s) * torch.pi * 0.5) ** 2 + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + def _alpha_cumprod(self, t, device): + if self.scaler > 1: + t = 1 - (1 - t) ** self.scaler + elif self.scaler < 1: + t = t**self.scaler + alpha_cumprod = torch.cos( + (t + self.s.to(device)) / (1 + self.s.to(device)) * torch.pi * 0.5 + ) ** 2 / self._init_alpha_cumprod.to(device) + return alpha_cumprod.clamp(0.0001, 0.9999) + + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): input sample + timestep (`int`, optional): current timestep + + Returns: + `torch.Tensor`: scaled input sample + """ + return sample + + def set_timesteps( + self, + num_inference_steps: int = None, + timesteps: Optional[List[int]] = None, + device: Union[str, torch.device] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain. Supporting function to be run before inference. + + Args: + num_inference_steps (`Dict[float, int]`): + the number of diffusion steps used when generating samples with a pre-trained model. If passed, then + `timesteps` must be `None`. + device (`str` or `torch.device`, optional): + the device to which the timesteps are moved to. {2 / 3: 20, 0.0: 10} + """ + if timesteps is None: + timesteps = torch.linspace(1.0, 0.0, num_inference_steps + 1, device=device) + if not isinstance(timesteps, torch.Tensor): + timesteps = torch.Tensor(timesteps).to(device) + self.timesteps = timesteps + + def step( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + generator=None, + return_dict: bool = True, + ) -> Union[DDPMWuerstchenSchedulerOutput, Tuple]: + """ + Predict the sample at the previous timestep by reversing the SDE. Core function to propagate the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + current instance of sample being created by diffusion process. + generator: random number generator. + return_dict (`bool`): option for returning tuple rather than DDPMWuerstchenSchedulerOutput class + + Returns: + [`DDPMWuerstchenSchedulerOutput`] or `tuple`: [`DDPMWuerstchenSchedulerOutput`] if `return_dict` is True, + otherwise a `tuple`. When returning a tuple, the first element is the sample tensor. + + """ + dtype = model_output.dtype + device = model_output.device + t = timestep + + prev_t = self.previous_timestep(t) + + alpha_cumprod = self._alpha_cumprod(t, device).view(t.size(0), *[1 for _ in sample.shape[1:]]) + alpha_cumprod_prev = self._alpha_cumprod(prev_t, device).view(prev_t.size(0), *[1 for _ in sample.shape[1:]]) + alpha = alpha_cumprod / alpha_cumprod_prev + + mu = (1.0 / alpha).sqrt() * (sample - (1 - alpha) * model_output / (1 - alpha_cumprod).sqrt()) + + std_noise = randn_tensor(mu.shape, generator=generator, device=model_output.device, dtype=model_output.dtype) + std = ((1 - alpha) * (1.0 - alpha_cumprod_prev) / (1.0 - alpha_cumprod)).sqrt() * std_noise + pred = mu + std * (prev_t != 0).float().view(prev_t.size(0), *[1 for _ in sample.shape[1:]]) + + if not return_dict: + return (pred.to(dtype),) + + return DDPMWuerstchenSchedulerOutput(prev_sample=pred.to(dtype)) + + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.Tensor, + ) -> torch.Tensor: + device = original_samples.device + dtype = original_samples.dtype + alpha_cumprod = self._alpha_cumprod(timesteps, device=device).view( + timesteps.size(0), *[1 for _ in original_samples.shape[1:]] + ) + noisy_samples = alpha_cumprod.sqrt() * original_samples + (1 - alpha_cumprod).sqrt() * noise + return noisy_samples.to(dtype=dtype) + + def __len__(self): + return self.config.num_train_timesteps + + def previous_timestep(self, timestep): + index = (self.timesteps - timestep[0]).abs().argmin().item() + prev_t = self.timesteps[index + 1][None].expand(timestep.shape[0]) + return prev_t diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_deis_multistep.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_deis_multistep.py new file mode 100644 index 0000000000000000000000000000000000000000..962dd339da7482a0a08a6b6bb9e5ed16d0a10463 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_deis_multistep.py @@ -0,0 +1,886 @@ +# Copyright 2024 FLAIR Lab and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: check https://huggingface.co/papers/2204.13902 and https://github.com/qsh-zh/deis for more info +# The codebase is modified based on https://github.com/huggingface/diffusers/blob/main/src/diffusers/schedulers/scheduling_dpmsolver_multistep.py + +import math +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import deprecate, is_scipy_available +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin, SchedulerOutput + + +if is_scipy_available(): + import scipy.stats + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +class DEISMultistepScheduler(SchedulerMixin, ConfigMixin): + """ + `DEISMultistepScheduler` is a fast high order solver for diffusion ordinary differential equations (ODEs). + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + solver_order (`int`, defaults to 2): + The DEIS order which can be `1` or `2` or `3`. It is recommended to use `solver_order=2` for guided + sampling, and `solver_order=3` for unconditional sampling. + prediction_type (`str`, defaults to `epsilon`): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + thresholding (`bool`, defaults to `False`): + Whether to use the "dynamic thresholding" method. This is unsuitable for latent-space diffusion models such + as Stable Diffusion. + dynamic_thresholding_ratio (`float`, defaults to 0.995): + The ratio for the dynamic thresholding method. Valid only when `thresholding=True`. + sample_max_value (`float`, defaults to 1.0): + The threshold value for dynamic thresholding. Valid only when `thresholding=True`. + algorithm_type (`str`, defaults to `deis`): + The algorithm type for the solver. + lower_order_final (`bool`, defaults to `True`): + Whether to use lower-order solvers in the final steps. Only valid for < 15 inference steps. + use_karras_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use Karras sigmas for step sizes in the noise schedule during the sampling process. If `True`, + the sigmas are determined according to a sequence of noise levels {σi}. + use_exponential_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use exponential sigmas for step sizes in the noise schedule during the sampling process. + use_beta_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use beta sigmas for step sizes in the noise schedule during the sampling process. Refer to [Beta + Sampling is All You Need](https://huggingface.co/papers/2407.12173) for more information. + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[np.ndarray] = None, + solver_order: int = 2, + prediction_type: str = "epsilon", + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + sample_max_value: float = 1.0, + algorithm_type: str = "deis", + solver_type: str = "logrho", + lower_order_final: bool = True, + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + use_flow_sigmas: Optional[bool] = False, + flow_shift: Optional[float] = 1.0, + timestep_spacing: str = "linspace", + steps_offset: int = 0, + ): + if self.config.use_beta_sigmas and not is_scipy_available(): + raise ImportError("Make sure to install scipy if you want to use beta sigmas.") + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + # Currently we only support VP-type noise schedule + self.alpha_t = torch.sqrt(self.alphas_cumprod) + self.sigma_t = torch.sqrt(1 - self.alphas_cumprod) + self.lambda_t = torch.log(self.alpha_t) - torch.log(self.sigma_t) + self.sigmas = ((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5 + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # settings for DEIS + if algorithm_type not in ["deis"]: + if algorithm_type in ["dpmsolver", "dpmsolver++"]: + self.register_to_config(algorithm_type="deis") + else: + raise NotImplementedError(f"{algorithm_type} is not implemented for {self.__class__}") + + if solver_type not in ["logrho"]: + if solver_type in ["midpoint", "heun", "bh1", "bh2"]: + self.register_to_config(solver_type="logrho") + else: + raise NotImplementedError(f"solver type {solver_type} is not implemented for {self.__class__}") + + # setable values + self.num_inference_steps = None + timesteps = np.linspace(0, num_train_timesteps - 1, num_train_timesteps, dtype=np.float32)[::-1].copy() + self.timesteps = torch.from_numpy(timesteps) + self.model_outputs = [None] * solver_order + self.lower_order_nums = 0 + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = ( + np.linspace(0, self.config.num_train_timesteps - 1, num_inference_steps + 1) + .round()[::-1][:-1] + .copy() + .astype(np.int64) + ) + elif self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // (num_inference_steps + 1) + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps + 1) * step_ratio).round()[::-1][:-1].copy().astype(np.int64) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = np.arange(self.config.num_train_timesteps, 0, -step_ratio).round().copy().astype(np.int64) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + log_sigmas = np.log(sigmas) + if self.config.use_karras_sigmas: + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_karras(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]).round() + sigmas = np.concatenate([sigmas, sigmas[-1:]]).astype(np.float32) + elif self.config.use_exponential_sigmas: + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + sigmas = np.concatenate([sigmas, sigmas[-1:]]).astype(np.float32) + elif self.config.use_beta_sigmas: + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + sigmas = np.concatenate([sigmas, sigmas[-1:]]).astype(np.float32) + elif self.config.use_flow_sigmas: + alphas = np.linspace(1, 1 / self.config.num_train_timesteps, num_inference_steps + 1) + sigmas = 1.0 - alphas + sigmas = np.flip(self.config.flow_shift * sigmas / (1 + (self.config.flow_shift - 1) * sigmas))[:-1].copy() + timesteps = (sigmas * self.config.num_train_timesteps).copy() + sigmas = np.concatenate([sigmas, sigmas[-1:]]).astype(np.float32) + else: + sigmas = np.interp(timesteps, np.arange(0, len(sigmas)), sigmas) + sigma_last = ((1 - self.alphas_cumprod[0]) / self.alphas_cumprod[0]) ** 0.5 + sigmas = np.concatenate([sigmas, [sigma_last]]).astype(np.float32) + + self.sigmas = torch.from_numpy(sigmas) + self.timesteps = torch.from_numpy(timesteps).to(device=device, dtype=torch.int64) + + self.num_inference_steps = len(timesteps) + + self.model_outputs = [ + None, + ] * self.config.solver_order + self.lower_order_nums = 0 + + # add an index counter for schedulers that allow duplicated timesteps + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler._threshold_sample + def _threshold_sample(self, sample: torch.Tensor) -> torch.Tensor: + """ + "Dynamic thresholding: At each sampling step we set s to a certain percentile absolute pixel value in xt0 (the + prediction of x_0 at timestep t), and if s > 1, then we threshold xt0 to the range [-s, s] and then divide by + s. Dynamic thresholding pushes saturated pixels (those near -1 and 1) inwards, thereby actively preventing + pixels from saturation at each step. We find that dynamic thresholding results in significantly better + photorealism as well as better image-text alignment, especially when using very large guidance weights." + + https://huggingface.co/papers/2205.11487 + """ + dtype = sample.dtype + batch_size, channels, *remaining_dims = sample.shape + + if dtype not in (torch.float32, torch.float64): + sample = sample.float() # upcast for quantile calculation, and clamp not implemented for cpu half + + # Flatten sample for doing quantile calculation along each image + sample = sample.reshape(batch_size, channels * np.prod(remaining_dims)) + + abs_sample = sample.abs() # "a certain percentile absolute pixel value" + + s = torch.quantile(abs_sample, self.config.dynamic_thresholding_ratio, dim=1) + s = torch.clamp( + s, min=1, max=self.config.sample_max_value + ) # When clamped to min=1, equivalent to standard clipping to [-1, 1] + s = s.unsqueeze(1) # (batch_size, 1) because clamp will broadcast along dim=0 + sample = torch.clamp(sample, -s, s) / s # "we threshold xt0 to the range [-s, s] and then divide by s" + + sample = sample.reshape(batch_size, channels, *remaining_dims) + sample = sample.to(dtype) + + return sample + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._sigma_to_t + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler._sigma_to_alpha_sigma_t + def _sigma_to_alpha_sigma_t(self, sigma): + if self.config.use_flow_sigmas: + alpha_t = 1 - sigma + sigma_t = sigma + else: + alpha_t = 1 / ((sigma**2 + 1) ** 0.5) + sigma_t = sigma * alpha_t + + return alpha_t, sigma_t + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_karras + def _convert_to_karras(self, in_sigmas: torch.Tensor, num_inference_steps) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_exponential + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_beta + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + def convert_model_output( + self, + model_output: torch.Tensor, + *args, + sample: torch.Tensor = None, + **kwargs, + ) -> torch.Tensor: + """ + Convert the model output to the corresponding type the DEIS algorithm needs. + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The converted model output. + """ + timestep = args[0] if len(args) > 0 else kwargs.pop("timestep", None) + if sample is None: + if len(args) > 1: + sample = args[1] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep is not None: + deprecate( + "timesteps", + "1.0.0", + "Passing `timesteps` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + if self.config.prediction_type == "epsilon": + x0_pred = (sample - sigma_t * model_output) / alpha_t + elif self.config.prediction_type == "sample": + x0_pred = model_output + elif self.config.prediction_type == "v_prediction": + x0_pred = alpha_t * sample - sigma_t * model_output + elif self.config.prediction_type == "flow_prediction": + sigma_t = self.sigmas[self.step_index] + x0_pred = sample - sigma_t * model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, " + "`v_prediction`, or `flow_prediction` for the DEISMultistepScheduler." + ) + + if self.config.thresholding: + x0_pred = self._threshold_sample(x0_pred) + + if self.config.algorithm_type == "deis": + return (sample - alpha_t * x0_pred) / sigma_t + else: + raise NotImplementedError("only support log-rho multistep deis now") + + def deis_first_order_update( + self, + model_output: torch.Tensor, + *args, + sample: torch.Tensor = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the first-order DEIS (equivalent to DDIM). + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + prev_timestep (`int`): + The previous discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + timestep = args[0] if len(args) > 0 else kwargs.pop("timestep", None) + prev_timestep = args[1] if len(args) > 1 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 2: + sample = args[2] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep is not None: + deprecate( + "timesteps", + "1.0.0", + "Passing `timesteps` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + sigma_t, sigma_s = self.sigmas[self.step_index + 1], self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s, sigma_s = self._sigma_to_alpha_sigma_t(sigma_s) + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s = torch.log(alpha_s) - torch.log(sigma_s) + + h = lambda_t - lambda_s + if self.config.algorithm_type == "deis": + x_t = (alpha_t / alpha_s) * sample - (sigma_t * (torch.exp(h) - 1.0)) * model_output + else: + raise NotImplementedError("only support log-rho multistep deis now") + return x_t + + def multistep_deis_second_order_update( + self, + model_output_list: List[torch.Tensor], + *args, + sample: torch.Tensor = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the second-order multistep DEIS. + + Args: + model_output_list (`List[torch.Tensor]`): + The direct outputs from learned diffusion model at current and latter timesteps. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + timestep_list = args[0] if len(args) > 0 else kwargs.pop("timestep_list", None) + prev_timestep = args[1] if len(args) > 1 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 2: + sample = args[2] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep_list is not None: + deprecate( + "timestep_list", + "1.0.0", + "Passing `timestep_list` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + sigma_t, sigma_s0, sigma_s1 = ( + self.sigmas[self.step_index + 1], + self.sigmas[self.step_index], + self.sigmas[self.step_index - 1], + ) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + alpha_s1, sigma_s1 = self._sigma_to_alpha_sigma_t(sigma_s1) + + m0, m1 = model_output_list[-1], model_output_list[-2] + + rho_t, rho_s0, rho_s1 = sigma_t / alpha_t, sigma_s0 / alpha_s0, sigma_s1 / alpha_s1 + + if self.config.algorithm_type == "deis": + + def ind_fn(t, b, c): + # Integrate[(log(t) - log(c)) / (log(b) - log(c)), {t}] + return t * (-np.log(c) + np.log(t) - 1) / (np.log(b) - np.log(c)) + + coef1 = ind_fn(rho_t, rho_s0, rho_s1) - ind_fn(rho_s0, rho_s0, rho_s1) + coef2 = ind_fn(rho_t, rho_s1, rho_s0) - ind_fn(rho_s0, rho_s1, rho_s0) + + x_t = alpha_t * (sample / alpha_s0 + coef1 * m0 + coef2 * m1) + return x_t + else: + raise NotImplementedError("only support log-rho multistep deis now") + + def multistep_deis_third_order_update( + self, + model_output_list: List[torch.Tensor], + *args, + sample: torch.Tensor = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the third-order multistep DEIS. + + Args: + model_output_list (`List[torch.Tensor]`): + The direct outputs from learned diffusion model at current and latter timesteps. + sample (`torch.Tensor`): + A current instance of a sample created by diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + + timestep_list = args[0] if len(args) > 0 else kwargs.pop("timestep_list", None) + prev_timestep = args[1] if len(args) > 1 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 2: + sample = args[2] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep_list is not None: + deprecate( + "timestep_list", + "1.0.0", + "Passing `timestep_list` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + sigma_t, sigma_s0, sigma_s1, sigma_s2 = ( + self.sigmas[self.step_index + 1], + self.sigmas[self.step_index], + self.sigmas[self.step_index - 1], + self.sigmas[self.step_index - 2], + ) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + alpha_s1, sigma_s1 = self._sigma_to_alpha_sigma_t(sigma_s1) + alpha_s2, sigma_s2 = self._sigma_to_alpha_sigma_t(sigma_s2) + + m0, m1, m2 = model_output_list[-1], model_output_list[-2], model_output_list[-3] + + rho_t, rho_s0, rho_s1, rho_s2 = ( + sigma_t / alpha_t, + sigma_s0 / alpha_s0, + sigma_s1 / alpha_s1, + sigma_s2 / alpha_s2, + ) + + if self.config.algorithm_type == "deis": + + def ind_fn(t, b, c, d): + # Integrate[(log(t) - log(c))(log(t) - log(d)) / (log(b) - log(c))(log(b) - log(d)), {t}] + numerator = t * ( + np.log(c) * (np.log(d) - np.log(t) + 1) + - np.log(d) * np.log(t) + + np.log(d) + + np.log(t) ** 2 + - 2 * np.log(t) + + 2 + ) + denominator = (np.log(b) - np.log(c)) * (np.log(b) - np.log(d)) + return numerator / denominator + + coef1 = ind_fn(rho_t, rho_s0, rho_s1, rho_s2) - ind_fn(rho_s0, rho_s0, rho_s1, rho_s2) + coef2 = ind_fn(rho_t, rho_s1, rho_s2, rho_s0) - ind_fn(rho_s0, rho_s1, rho_s2, rho_s0) + coef3 = ind_fn(rho_t, rho_s2, rho_s0, rho_s1) - ind_fn(rho_s0, rho_s2, rho_s0, rho_s1) + + x_t = alpha_t * (sample / alpha_s0 + coef1 * m0 + coef2 * m1 + coef3 * m2) + + return x_t + else: + raise NotImplementedError("only support log-rho multistep deis now") + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + index_candidates = (schedule_timesteps == timestep).nonzero() + + if len(index_candidates) == 0: + step_index = len(self.timesteps) - 1 + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + elif len(index_candidates) > 1: + step_index = index_candidates[1].item() + else: + step_index = index_candidates[0].item() + + return step_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler._init_step_index + def _init_step_index(self, timestep): + """ + Initialize the step_index counter for the scheduler. + """ + + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.Tensor, + timestep: Union[int, torch.Tensor], + sample: torch.Tensor, + return_dict: bool = True, + ) -> Union[SchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the sample with + the multistep DEIS. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_utils.SchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + if self.step_index is None: + self._init_step_index(timestep) + + lower_order_final = ( + (self.step_index == len(self.timesteps) - 1) and self.config.lower_order_final and len(self.timesteps) < 15 + ) + lower_order_second = ( + (self.step_index == len(self.timesteps) - 2) and self.config.lower_order_final and len(self.timesteps) < 15 + ) + + model_output = self.convert_model_output(model_output, sample=sample) + for i in range(self.config.solver_order - 1): + self.model_outputs[i] = self.model_outputs[i + 1] + self.model_outputs[-1] = model_output + + if self.config.solver_order == 1 or self.lower_order_nums < 1 or lower_order_final: + prev_sample = self.deis_first_order_update(model_output, sample=sample) + elif self.config.solver_order == 2 or self.lower_order_nums < 2 or lower_order_second: + prev_sample = self.multistep_deis_second_order_update(self.model_outputs, sample=sample) + else: + prev_sample = self.multistep_deis_third_order_update(self.model_outputs, sample=sample) + + if self.lower_order_nums < self.config.solver_order: + self.lower_order_nums += 1 + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return (prev_sample,) + + return SchedulerOutput(prev_sample=prev_sample) + + def scale_model_input(self, sample: torch.Tensor, *args, **kwargs) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # begin_index is None when the scheduler is used for training or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + noisy_samples = alpha_t * original_samples + sigma_t * noise + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpm_cogvideox.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpm_cogvideox.py new file mode 100644 index 0000000000000000000000000000000000000000..ed15f04bd10ca4f7097d9d566f93dc5c873aee92 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpm_cogvideox.py @@ -0,0 +1,489 @@ +# Copyright 2024 The CogVideoX team, Tsinghua University & ZhipuAI and The HuggingFace Team. +# All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This code is strongly influenced by https://github.com/pesser/pytorch_diffusion +# and https://github.com/hojonathanho/diffusion + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->DDIM +class DDIMSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +def rescale_zero_terminal_snr(alphas_cumprod): + """ + Rescales betas to have zero terminal SNR Based on https://huggingface.co/papers/2305.08891 (Algorithm 1) + + + Args: + betas (`torch.Tensor`): + the betas that the scheduler is being initialized with. + + Returns: + `torch.Tensor`: rescaled betas with zero terminal SNR + """ + + alphas_bar_sqrt = alphas_cumprod.sqrt() + + # Store old values. + alphas_bar_sqrt_0 = alphas_bar_sqrt[0].clone() + alphas_bar_sqrt_T = alphas_bar_sqrt[-1].clone() + + # Shift so the last timestep is zero. + alphas_bar_sqrt -= alphas_bar_sqrt_T + + # Scale so the first timestep is back to the old value. + alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T) + + # Convert alphas_bar_sqrt to betas + alphas_bar = alphas_bar_sqrt**2 # Revert sqrt + + return alphas_bar + + +class CogVideoXDPMScheduler(SchedulerMixin, ConfigMixin): + """ + `DDIMScheduler` extends the denoising procedure introduced in denoising diffusion probabilistic models (DDPMs) with + non-Markovian guidance. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + clip_sample (`bool`, defaults to `True`): + Clip the predicted sample for numerical stability. + clip_sample_range (`float`, defaults to 1.0): + The maximum magnitude for sample clipping. Valid only when `clip_sample=True`. + set_alpha_to_one (`bool`, defaults to `True`): + Each diffusion step uses the alphas product value at that step and at the previous one. For the final step + there is no previous alpha. When this option is `True` the previous alpha product is fixed to `1`, + otherwise it uses the alpha value at step 0. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + thresholding (`bool`, defaults to `False`): + Whether to use the "dynamic thresholding" method. This is unsuitable for latent-space diffusion models such + as Stable Diffusion. + dynamic_thresholding_ratio (`float`, defaults to 0.995): + The ratio for the dynamic thresholding method. Valid only when `thresholding=True`. + sample_max_value (`float`, defaults to 1.0): + The threshold value for dynamic thresholding. Valid only when `thresholding=True`. + timestep_spacing (`str`, defaults to `"leading"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + rescale_betas_zero_snr (`bool`, defaults to `False`): + Whether to rescale the betas to have zero terminal SNR. This enables the model to generate very bright and + dark samples instead of limiting it to samples with medium brightness. Loosely related to + [`--offset_noise`](https://github.com/huggingface/diffusers/blob/74fd735eb073eb1d774b1ab4154a0876eb82f055/examples/dreambooth/train_dreambooth.py#L506). + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.00085, + beta_end: float = 0.0120, + beta_schedule: str = "scaled_linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + clip_sample: bool = True, + set_alpha_to_one: bool = True, + steps_offset: int = 0, + prediction_type: str = "epsilon", + clip_sample_range: float = 1.0, + sample_max_value: float = 1.0, + timestep_spacing: str = "leading", + rescale_betas_zero_snr: bool = False, + snr_shift_scale: float = 3.0, + ): + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float64) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + # Modify: SNR shift following SD3 + self.alphas_cumprod = self.alphas_cumprod / (snr_shift_scale + (1 - snr_shift_scale) * self.alphas_cumprod) + + # Rescale for zero SNR + if rescale_betas_zero_snr: + self.alphas_cumprod = rescale_zero_terminal_snr(self.alphas_cumprod) + + # At every step in ddim, we are looking into the previous alphas_cumprod + # For the final step, there is no previous alphas_cumprod because we are already at 0 + # `set_alpha_to_one` decides whether we set this parameter simply to one or + # whether we use the final alpha of the "non-previous" one. + self.final_alpha_cumprod = torch.tensor(1.0) if set_alpha_to_one else self.alphas_cumprod[0] + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # setable values + self.num_inference_steps = None + self.timesteps = torch.from_numpy(np.arange(0, num_train_timesteps)[::-1].copy().astype(np.int64)) + + def _get_variance(self, timestep, prev_timestep): + alpha_prod_t = self.alphas_cumprod[timestep] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + variance = (beta_prod_t_prev / beta_prod_t) * (1 - alpha_prod_t / alpha_prod_t_prev) + + return variance + + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + """ + + if num_inference_steps > self.config.num_train_timesteps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `self.config.train_timesteps`:" + f" {self.config.num_train_timesteps} as the unet model trained with this scheduler can only handle" + f" maximal {self.config.num_train_timesteps} timesteps." + ) + + self.num_inference_steps = num_inference_steps + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = ( + np.linspace(0, self.config.num_train_timesteps - 1, num_inference_steps) + .round()[::-1] + .copy() + .astype(np.int64) + ) + elif self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.int64) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = np.round(np.arange(self.config.num_train_timesteps, 0, -step_ratio)).astype(np.int64) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'leading' or 'trailing'." + ) + + self.timesteps = torch.from_numpy(timesteps).to(device) + + def get_variables(self, alpha_prod_t, alpha_prod_t_prev, alpha_prod_t_back=None): + lamb = ((alpha_prod_t / (1 - alpha_prod_t)) ** 0.5).log() + lamb_next = ((alpha_prod_t_prev / (1 - alpha_prod_t_prev)) ** 0.5).log() + h = lamb_next - lamb + + if alpha_prod_t_back is not None: + lamb_previous = ((alpha_prod_t_back / (1 - alpha_prod_t_back)) ** 0.5).log() + h_last = lamb - lamb_previous + r = h_last / h + return h, r, lamb, lamb_next + else: + return h, None, lamb, lamb_next + + def get_mult(self, h, r, alpha_prod_t, alpha_prod_t_prev, alpha_prod_t_back): + mult1 = ((1 - alpha_prod_t_prev) / (1 - alpha_prod_t)) ** 0.5 * (-h).exp() + mult2 = (-2 * h).expm1() * alpha_prod_t_prev**0.5 + + if alpha_prod_t_back is not None: + mult3 = 1 + 1 / (2 * r) + mult4 = 1 / (2 * r) + return mult1, mult2, mult3, mult4 + else: + return mult1, mult2 + + def step( + self, + model_output: torch.Tensor, + old_pred_original_sample: torch.Tensor, + timestep: int, + timestep_back: int, + sample: torch.Tensor, + eta: float = 0.0, + use_clipped_model_output: bool = False, + generator=None, + variance_noise: Optional[torch.Tensor] = None, + return_dict: bool = False, + ) -> Union[DDIMSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + eta (`float`): + The weight of noise for added noise in diffusion step. + use_clipped_model_output (`bool`, defaults to `False`): + If `True`, computes "corrected" `model_output` from the clipped predicted original sample. Necessary + because predicted original sample is clipped to [-1, 1] when `self.config.clip_sample` is `True`. If no + clipping has happened, "corrected" `model_output` would coincide with the one provided as input and + `use_clipped_model_output` has no effect. + generator (`torch.Generator`, *optional*): + A random number generator. + variance_noise (`torch.Tensor`): + Alternative to generating noise with `generator` by directly providing the noise for the variance + itself. Useful for methods such as [`CycleDiffusion`]. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_ddim.DDIMSchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_ddim.DDIMSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_ddim.DDIMSchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + # See formulas (12) and (16) of DDIM paper https://huggingface.co/papers/2010.02502 + # Ideally, read DDIM paper in-detail understanding + + # Notation ( -> + # - pred_noise_t -> e_theta(x_t, t) + # - pred_original_sample -> f_theta(x_t, t) or x_0 + # - std_dev_t -> sigma_t + # - eta -> η + # - pred_sample_direction -> "direction pointing to x_t" + # - pred_prev_sample -> "x_t-1" + + # 1. get previous step value (=t-1) + prev_timestep = timestep - self.config.num_train_timesteps // self.num_inference_steps + + # 2. compute alphas, betas + alpha_prod_t = self.alphas_cumprod[timestep] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + alpha_prod_t_back = self.alphas_cumprod[timestep_back] if timestep_back is not None else None + + beta_prod_t = 1 - alpha_prod_t + + # 3. compute predicted original sample from predicted noise also called + # "predicted x_0" of formula (12) from https://huggingface.co/papers/2010.02502 + # To make style tests pass, commented out `pred_epsilon` as it is an unused variable + if self.config.prediction_type == "epsilon": + pred_original_sample = (sample - beta_prod_t ** (0.5) * model_output) / alpha_prod_t ** (0.5) + # pred_epsilon = model_output + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + # pred_epsilon = (sample - alpha_prod_t ** (0.5) * pred_original_sample) / beta_prod_t ** (0.5) + elif self.config.prediction_type == "v_prediction": + pred_original_sample = (alpha_prod_t**0.5) * sample - (beta_prod_t**0.5) * model_output + # pred_epsilon = (alpha_prod_t**0.5) * model_output + (beta_prod_t**0.5) * sample + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, or" + " `v_prediction`" + ) + + h, r, lamb, lamb_next = self.get_variables(alpha_prod_t, alpha_prod_t_prev, alpha_prod_t_back) + mult = list(self.get_mult(h, r, alpha_prod_t, alpha_prod_t_prev, alpha_prod_t_back)) + mult_noise = (1 - alpha_prod_t_prev) ** 0.5 * (1 - (-2 * h).exp()) ** 0.5 + + noise = randn_tensor(sample.shape, generator=generator, device=sample.device, dtype=sample.dtype) + prev_sample = mult[0] * sample - mult[1] * pred_original_sample + mult_noise * noise + + if old_pred_original_sample is None or prev_timestep < 0: + # Save a network evaluation if all noise levels are 0 or on the first step + return prev_sample, pred_original_sample + else: + denoised_d = mult[2] * pred_original_sample - mult[3] * old_pred_original_sample + noise = randn_tensor(sample.shape, generator=generator, device=sample.device, dtype=sample.dtype) + x_advanced = mult[0] * sample - mult[1] * denoised_d + mult_noise * noise + + prev_sample = x_advanced + + if not return_dict: + return (prev_sample, pred_original_sample) + + return DDIMSchedulerOutput(prev_sample=prev_sample, pred_original_sample=pred_original_sample) + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as original_samples + # Move the self.alphas_cumprod to device to avoid redundant CPU to GPU data movement + # for the subsequent add_noise calls + self.alphas_cumprod = self.alphas_cumprod.to(device=original_samples.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=original_samples.dtype) + timesteps = timesteps.to(original_samples.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(original_samples.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(original_samples.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + noisy_samples = sqrt_alpha_prod * original_samples + sqrt_one_minus_alpha_prod * noise + return noisy_samples + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.get_velocity + def get_velocity(self, sample: torch.Tensor, noise: torch.Tensor, timesteps: torch.IntTensor) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as sample + self.alphas_cumprod = self.alphas_cumprod.to(device=sample.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=sample.dtype) + timesteps = timesteps.to(sample.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(sample.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(sample.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + velocity = sqrt_alpha_prod * noise - sqrt_one_minus_alpha_prod * sample + return velocity + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_multistep.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_multistep.py new file mode 100644 index 0000000000000000000000000000000000000000..33a5ccdf22e4cac2f2bb610bd409854adb16e203 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_multistep.py @@ -0,0 +1,1174 @@ +# Copyright 2024 TSAIL Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/LuChengTHU/dpm-solver + +import math +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import deprecate, is_scipy_available +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin, SchedulerOutput + + +if is_scipy_available(): + import scipy.stats + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +# Copied from diffusers.schedulers.scheduling_ddim.rescale_zero_terminal_snr +def rescale_zero_terminal_snr(betas): + """ + Rescales betas to have zero terminal SNR Based on https://huggingface.co/papers/2305.08891 (Algorithm 1) + + + Args: + betas (`torch.Tensor`): + the betas that the scheduler is being initialized with. + + Returns: + `torch.Tensor`: rescaled betas with zero terminal SNR + """ + # Convert betas to alphas_bar_sqrt + alphas = 1.0 - betas + alphas_cumprod = torch.cumprod(alphas, dim=0) + alphas_bar_sqrt = alphas_cumprod.sqrt() + + # Store old values. + alphas_bar_sqrt_0 = alphas_bar_sqrt[0].clone() + alphas_bar_sqrt_T = alphas_bar_sqrt[-1].clone() + + # Shift so the last timestep is zero. + alphas_bar_sqrt -= alphas_bar_sqrt_T + + # Scale so the first timestep is back to the old value. + alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T) + + # Convert alphas_bar_sqrt to betas + alphas_bar = alphas_bar_sqrt**2 # Revert sqrt + alphas = alphas_bar[1:] / alphas_bar[:-1] # Revert cumprod + alphas = torch.cat([alphas_bar[0:1], alphas]) + betas = 1 - alphas + + return betas + + +class DPMSolverMultistepScheduler(SchedulerMixin, ConfigMixin): + """ + `DPMSolverMultistepScheduler` is a fast dedicated high-order solver for diffusion ODEs. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + solver_order (`int`, defaults to 2): + The DPMSolver order which can be `1` or `2` or `3`. It is recommended to use `solver_order=2` for guided + sampling, and `solver_order=3` for unconditional sampling. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample), `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper), or `flow_prediction`. + thresholding (`bool`, defaults to `False`): + Whether to use the "dynamic thresholding" method. This is unsuitable for latent-space diffusion models such + as Stable Diffusion. + dynamic_thresholding_ratio (`float`, defaults to 0.995): + The ratio for the dynamic thresholding method. Valid only when `thresholding=True`. + sample_max_value (`float`, defaults to 1.0): + The threshold value for dynamic thresholding. Valid only when `thresholding=True` and + `algorithm_type="dpmsolver++"`. + algorithm_type (`str`, defaults to `dpmsolver++`): + Algorithm type for the solver; can be `dpmsolver`, `dpmsolver++`, `sde-dpmsolver` or `sde-dpmsolver++`. The + `dpmsolver` type implements the algorithms in the [DPMSolver](https://huggingface.co/papers/2206.00927) + paper, and the `dpmsolver++` type implements the algorithms in the + [DPMSolver++](https://huggingface.co/papers/2211.01095) paper. It is recommended to use `dpmsolver++` or + `sde-dpmsolver++` with `solver_order=2` for guided sampling like in Stable Diffusion. + solver_type (`str`, defaults to `midpoint`): + Solver type for the second-order solver; can be `midpoint` or `heun`. The solver type slightly affects the + sample quality, especially for a small number of steps. It is recommended to use `midpoint` solvers. + lower_order_final (`bool`, defaults to `True`): + Whether to use lower-order solvers in the final steps. Only valid for < 15 inference steps. This can + stabilize the sampling of DPMSolver for steps < 15, especially for steps <= 10. + euler_at_final (`bool`, defaults to `False`): + Whether to use Euler's method in the final step. It is a trade-off between numerical stability and detail + richness. This can stabilize the sampling of the SDE variant of DPMSolver for small number of inference + steps, but sometimes may result in blurring. + use_karras_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use Karras sigmas for step sizes in the noise schedule during the sampling process. If `True`, + the sigmas are determined according to a sequence of noise levels {σi}. + use_exponential_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use exponential sigmas for step sizes in the noise schedule during the sampling process. + use_beta_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use beta sigmas for step sizes in the noise schedule during the sampling process. Refer to [Beta + Sampling is All You Need](https://huggingface.co/papers/2407.12173) for more information. + use_lu_lambdas (`bool`, *optional*, defaults to `False`): + Whether to use the uniform-logSNR for step sizes proposed by Lu's DPM-Solver in the noise schedule during + the sampling process. If `True`, the sigmas and time steps are determined according to a sequence of + `lambda(t)`. + use_flow_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use flow sigmas for step sizes in the noise schedule during the sampling process. + flow_shift (`float`, *optional*, defaults to 1.0): + The shift value for the timestep schedule for flow matching. + final_sigmas_type (`str`, defaults to `"zero"`): + The final `sigma` value for the noise schedule during the sampling process. If `"sigma_min"`, the final + sigma is the same as the last sigma in the training schedule. If `zero`, the final sigma is set to 0. + lambda_min_clipped (`float`, defaults to `-inf`): + Clipping threshold for the minimum value of `lambda(t)` for numerical stability. This is critical for the + cosine (`squaredcos_cap_v2`) noise schedule. + variance_type (`str`, *optional*): + Set to "learned" or "learned_range" for diffusion models that predict variance. If set, the model's output + contains the predicted Gaussian variance. + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + rescale_betas_zero_snr (`bool`, defaults to `False`): + Whether to rescale the betas to have zero terminal SNR. This enables the model to generate very bright and + dark samples instead of limiting it to samples with medium brightness. Loosely related to + [`--offset_noise`](https://github.com/huggingface/diffusers/blob/74fd735eb073eb1d774b1ab4154a0876eb82f055/examples/dreambooth/train_dreambooth.py#L506). + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + solver_order: int = 2, + prediction_type: str = "epsilon", + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + sample_max_value: float = 1.0, + algorithm_type: str = "dpmsolver++", + solver_type: str = "midpoint", + lower_order_final: bool = True, + euler_at_final: bool = False, + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + use_lu_lambdas: Optional[bool] = False, + use_flow_sigmas: Optional[bool] = False, + flow_shift: Optional[float] = 1.0, + final_sigmas_type: Optional[str] = "zero", # "zero", "sigma_min" + lambda_min_clipped: float = -float("inf"), + variance_type: Optional[str] = None, + timestep_spacing: str = "linspace", + steps_offset: int = 0, + rescale_betas_zero_snr: bool = False, + ): + if self.config.use_beta_sigmas and not is_scipy_available(): + raise ImportError("Make sure to install scipy if you want to use beta sigmas.") + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if algorithm_type in ["dpmsolver", "sde-dpmsolver"]: + deprecation_message = f"algorithm_type {algorithm_type} is deprecated and will be removed in a future version. Choose from `dpmsolver++` or `sde-dpmsolver++` instead" + deprecate("algorithm_types dpmsolver and sde-dpmsolver", "1.0.0", deprecation_message) + + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + if rescale_betas_zero_snr: + self.betas = rescale_zero_terminal_snr(self.betas) + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + if rescale_betas_zero_snr: + # Close to 0 without being 0 so first sigma is not inf + # FP16 smallest positive subnormal works well here + self.alphas_cumprod[-1] = 2**-24 + + # Currently we only support VP-type noise schedule + self.alpha_t = torch.sqrt(self.alphas_cumprod) + self.sigma_t = torch.sqrt(1 - self.alphas_cumprod) + self.lambda_t = torch.log(self.alpha_t) - torch.log(self.sigma_t) + self.sigmas = ((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5 + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # settings for DPM-Solver + if algorithm_type not in ["dpmsolver", "dpmsolver++", "sde-dpmsolver", "sde-dpmsolver++"]: + if algorithm_type == "deis": + self.register_to_config(algorithm_type="dpmsolver++") + else: + raise NotImplementedError(f"{algorithm_type} is not implemented for {self.__class__}") + + if solver_type not in ["midpoint", "heun"]: + if solver_type in ["logrho", "bh1", "bh2"]: + self.register_to_config(solver_type="midpoint") + else: + raise NotImplementedError(f"{solver_type} is not implemented for {self.__class__}") + + if algorithm_type not in ["dpmsolver++", "sde-dpmsolver++"] and final_sigmas_type == "zero": + raise ValueError( + f"`final_sigmas_type` {final_sigmas_type} is not supported for `algorithm_type` {algorithm_type}. Please choose `sigma_min` instead." + ) + + # setable values + self.num_inference_steps = None + timesteps = np.linspace(0, num_train_timesteps - 1, num_train_timesteps, dtype=np.float32)[::-1].copy() + self.timesteps = torch.from_numpy(timesteps) + self.model_outputs = [None] * solver_order + self.lower_order_nums = 0 + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def set_timesteps( + self, + num_inference_steps: int = None, + device: Union[str, torch.device] = None, + timesteps: Optional[List[int]] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + timesteps (`List[int]`, *optional*): + Custom timesteps used to support arbitrary timesteps schedule. If `None`, timesteps will be generated + based on the `timestep_spacing` attribute. If `timesteps` is passed, `num_inference_steps` and `sigmas` + must be `None`, and `timestep_spacing` attribute will be ignored. + """ + if num_inference_steps is None and timesteps is None: + raise ValueError("Must pass exactly one of `num_inference_steps` or `timesteps`.") + if num_inference_steps is not None and timesteps is not None: + raise ValueError("Can only pass one of `num_inference_steps` or `custom_timesteps`.") + if timesteps is not None and self.config.use_karras_sigmas: + raise ValueError("Cannot use `timesteps` with `config.use_karras_sigmas = True`") + if timesteps is not None and self.config.use_lu_lambdas: + raise ValueError("Cannot use `timesteps` with `config.use_lu_lambdas = True`") + if timesteps is not None and self.config.use_exponential_sigmas: + raise ValueError("Cannot set `timesteps` with `config.use_exponential_sigmas = True`.") + if timesteps is not None and self.config.use_beta_sigmas: + raise ValueError("Cannot set `timesteps` with `config.use_beta_sigmas = True`.") + + if timesteps is not None: + timesteps = np.array(timesteps).astype(np.int64) + else: + # Clipping the minimum of all lambda(t) for numerical stability. + # This is critical for cosine (squaredcos_cap_v2) noise schedule. + clipped_idx = torch.searchsorted(torch.flip(self.lambda_t, [0]), self.config.lambda_min_clipped) + last_timestep = ((self.config.num_train_timesteps - clipped_idx).numpy()).item() + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = ( + np.linspace(0, last_timestep - 1, num_inference_steps + 1) + .round()[::-1][:-1] + .copy() + .astype(np.int64) + ) + elif self.config.timestep_spacing == "leading": + step_ratio = last_timestep // (num_inference_steps + 1) + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = ( + (np.arange(0, num_inference_steps + 1) * step_ratio).round()[::-1][:-1].copy().astype(np.int64) + ) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = np.arange(last_timestep, 0, -step_ratio).round().copy().astype(np.int64) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + log_sigmas = np.log(sigmas) + + if self.config.use_karras_sigmas: + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_karras(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + if self.config.beta_schedule != "squaredcos_cap_v2": + timesteps = timesteps.round() + elif self.config.use_lu_lambdas: + lambdas = np.flip(log_sigmas.copy()) + lambdas = self._convert_to_lu(in_lambdas=lambdas, num_inference_steps=num_inference_steps) + sigmas = np.exp(lambdas) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + if self.config.beta_schedule != "squaredcos_cap_v2": + timesteps = timesteps.round() + elif self.config.use_exponential_sigmas: + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + elif self.config.use_beta_sigmas: + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + elif self.config.use_flow_sigmas: + alphas = np.linspace(1, 1 / self.config.num_train_timesteps, num_inference_steps + 1) + sigmas = 1.0 - alphas + sigmas = np.flip(self.config.flow_shift * sigmas / (1 + (self.config.flow_shift - 1) * sigmas))[:-1].copy() + timesteps = (sigmas * self.config.num_train_timesteps).copy() + else: + sigmas = np.interp(timesteps, np.arange(0, len(sigmas)), sigmas) + + if self.config.final_sigmas_type == "sigma_min": + sigma_last = ((1 - self.alphas_cumprod[0]) / self.alphas_cumprod[0]) ** 0.5 + elif self.config.final_sigmas_type == "zero": + sigma_last = 0 + else: + raise ValueError( + f"`final_sigmas_type` must be one of 'zero', or 'sigma_min', but got {self.config.final_sigmas_type}" + ) + + sigmas = np.concatenate([sigmas, [sigma_last]]).astype(np.float32) + + self.sigmas = torch.from_numpy(sigmas) + self.timesteps = torch.from_numpy(timesteps).to(device=device, dtype=torch.int64) + + self.num_inference_steps = len(timesteps) + + self.model_outputs = [ + None, + ] * self.config.solver_order + self.lower_order_nums = 0 + + # add an index counter for schedulers that allow duplicated timesteps + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler._threshold_sample + def _threshold_sample(self, sample: torch.Tensor) -> torch.Tensor: + """ + "Dynamic thresholding: At each sampling step we set s to a certain percentile absolute pixel value in xt0 (the + prediction of x_0 at timestep t), and if s > 1, then we threshold xt0 to the range [-s, s] and then divide by + s. Dynamic thresholding pushes saturated pixels (those near -1 and 1) inwards, thereby actively preventing + pixels from saturation at each step. We find that dynamic thresholding results in significantly better + photorealism as well as better image-text alignment, especially when using very large guidance weights." + + https://huggingface.co/papers/2205.11487 + """ + dtype = sample.dtype + batch_size, channels, *remaining_dims = sample.shape + + if dtype not in (torch.float32, torch.float64): + sample = sample.float() # upcast for quantile calculation, and clamp not implemented for cpu half + + # Flatten sample for doing quantile calculation along each image + sample = sample.reshape(batch_size, channels * np.prod(remaining_dims)) + + abs_sample = sample.abs() # "a certain percentile absolute pixel value" + + s = torch.quantile(abs_sample, self.config.dynamic_thresholding_ratio, dim=1) + s = torch.clamp( + s, min=1, max=self.config.sample_max_value + ) # When clamped to min=1, equivalent to standard clipping to [-1, 1] + s = s.unsqueeze(1) # (batch_size, 1) because clamp will broadcast along dim=0 + sample = torch.clamp(sample, -s, s) / s # "we threshold xt0 to the range [-s, s] and then divide by s" + + sample = sample.reshape(batch_size, channels, *remaining_dims) + sample = sample.to(dtype) + + return sample + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._sigma_to_t + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + def _sigma_to_alpha_sigma_t(self, sigma): + if self.config.use_flow_sigmas: + alpha_t = 1 - sigma + sigma_t = sigma + else: + alpha_t = 1 / ((sigma**2 + 1) ** 0.5) + sigma_t = sigma * alpha_t + + return alpha_t, sigma_t + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_karras + def _convert_to_karras(self, in_sigmas: torch.Tensor, num_inference_steps) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + def _convert_to_lu(self, in_lambdas: torch.Tensor, num_inference_steps) -> torch.Tensor: + """Constructs the noise schedule of Lu et al. (2022).""" + + lambda_min: float = in_lambdas[-1].item() + lambda_max: float = in_lambdas[0].item() + + rho = 1.0 # 1.0 is the value used in the paper + ramp = np.linspace(0, 1, num_inference_steps) + min_inv_rho = lambda_min ** (1 / rho) + max_inv_rho = lambda_max ** (1 / rho) + lambdas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return lambdas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_exponential + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_beta + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + def convert_model_output( + self, + model_output: torch.Tensor, + *args, + sample: torch.Tensor = None, + **kwargs, + ) -> torch.Tensor: + """ + Convert the model output to the corresponding type the DPMSolver/DPMSolver++ algorithm needs. DPM-Solver is + designed to discretize an integral of the noise prediction model, and DPM-Solver++ is designed to discretize an + integral of the data prediction model. + + + + The algorithm and model type are decoupled. You can use either DPMSolver or DPMSolver++ for both noise + prediction and data prediction models. + + + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The converted model output. + """ + timestep = args[0] if len(args) > 0 else kwargs.pop("timestep", None) + if sample is None: + if len(args) > 1: + sample = args[1] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep is not None: + deprecate( + "timesteps", + "1.0.0", + "Passing `timesteps` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + # DPM-Solver++ needs to solve an integral of the data prediction model. + if self.config.algorithm_type in ["dpmsolver++", "sde-dpmsolver++"]: + if self.config.prediction_type == "epsilon": + # DPM-Solver and DPM-Solver++ only need the "mean" output. + if self.config.variance_type in ["learned", "learned_range"]: + model_output = model_output[:, :3] + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + x0_pred = (sample - sigma_t * model_output) / alpha_t + elif self.config.prediction_type == "sample": + x0_pred = model_output + elif self.config.prediction_type == "v_prediction": + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + x0_pred = alpha_t * sample - sigma_t * model_output + elif self.config.prediction_type == "flow_prediction": + sigma_t = self.sigmas[self.step_index] + x0_pred = sample - sigma_t * model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, " + "`v_prediction`, or `flow_prediction` for the DPMSolverMultistepScheduler." + ) + + if self.config.thresholding: + x0_pred = self._threshold_sample(x0_pred) + + return x0_pred + + # DPM-Solver needs to solve an integral of the noise prediction model. + elif self.config.algorithm_type in ["dpmsolver", "sde-dpmsolver"]: + if self.config.prediction_type == "epsilon": + # DPM-Solver and DPM-Solver++ only need the "mean" output. + if self.config.variance_type in ["learned", "learned_range"]: + epsilon = model_output[:, :3] + else: + epsilon = model_output + elif self.config.prediction_type == "sample": + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + epsilon = (sample - alpha_t * model_output) / sigma_t + elif self.config.prediction_type == "v_prediction": + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + epsilon = alpha_t * model_output + sigma_t * sample + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, or" + " `v_prediction` for the DPMSolverMultistepScheduler." + ) + + if self.config.thresholding: + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + x0_pred = (sample - sigma_t * epsilon) / alpha_t + x0_pred = self._threshold_sample(x0_pred) + epsilon = (sample - alpha_t * x0_pred) / sigma_t + + return epsilon + + def dpm_solver_first_order_update( + self, + model_output: torch.Tensor, + *args, + sample: torch.Tensor = None, + noise: Optional[torch.Tensor] = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the first-order DPMSolver (equivalent to DDIM). + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + timestep = args[0] if len(args) > 0 else kwargs.pop("timestep", None) + prev_timestep = args[1] if len(args) > 1 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 2: + sample = args[2] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep is not None: + deprecate( + "timesteps", + "1.0.0", + "Passing `timesteps` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + sigma_t, sigma_s = self.sigmas[self.step_index + 1], self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s, sigma_s = self._sigma_to_alpha_sigma_t(sigma_s) + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s = torch.log(alpha_s) - torch.log(sigma_s) + + h = lambda_t - lambda_s + if self.config.algorithm_type == "dpmsolver++": + x_t = (sigma_t / sigma_s) * sample - (alpha_t * (torch.exp(-h) - 1.0)) * model_output + elif self.config.algorithm_type == "dpmsolver": + x_t = (alpha_t / alpha_s) * sample - (sigma_t * (torch.exp(h) - 1.0)) * model_output + elif self.config.algorithm_type == "sde-dpmsolver++": + assert noise is not None + x_t = ( + (sigma_t / sigma_s * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * model_output + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + elif self.config.algorithm_type == "sde-dpmsolver": + assert noise is not None + x_t = ( + (alpha_t / alpha_s) * sample + - 2.0 * (sigma_t * (torch.exp(h) - 1.0)) * model_output + + sigma_t * torch.sqrt(torch.exp(2 * h) - 1.0) * noise + ) + return x_t + + def multistep_dpm_solver_second_order_update( + self, + model_output_list: List[torch.Tensor], + *args, + sample: torch.Tensor = None, + noise: Optional[torch.Tensor] = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the second-order multistep DPMSolver. + + Args: + model_output_list (`List[torch.Tensor]`): + The direct outputs from learned diffusion model at current and latter timesteps. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + timestep_list = args[0] if len(args) > 0 else kwargs.pop("timestep_list", None) + prev_timestep = args[1] if len(args) > 1 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 2: + sample = args[2] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep_list is not None: + deprecate( + "timestep_list", + "1.0.0", + "Passing `timestep_list` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + sigma_t, sigma_s0, sigma_s1 = ( + self.sigmas[self.step_index + 1], + self.sigmas[self.step_index], + self.sigmas[self.step_index - 1], + ) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + alpha_s1, sigma_s1 = self._sigma_to_alpha_sigma_t(sigma_s1) + + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s0 = torch.log(alpha_s0) - torch.log(sigma_s0) + lambda_s1 = torch.log(alpha_s1) - torch.log(sigma_s1) + + m0, m1 = model_output_list[-1], model_output_list[-2] + + h, h_0 = lambda_t - lambda_s0, lambda_s0 - lambda_s1 + r0 = h_0 / h + D0, D1 = m0, (1.0 / r0) * (m0 - m1) + if self.config.algorithm_type == "dpmsolver++": + # See https://huggingface.co/papers/2211.01095 for detailed derivations + if self.config.solver_type == "midpoint": + x_t = ( + (sigma_t / sigma_s0) * sample + - (alpha_t * (torch.exp(-h) - 1.0)) * D0 + - 0.5 * (alpha_t * (torch.exp(-h) - 1.0)) * D1 + ) + elif self.config.solver_type == "heun": + x_t = ( + (sigma_t / sigma_s0) * sample + - (alpha_t * (torch.exp(-h) - 1.0)) * D0 + + (alpha_t * ((torch.exp(-h) - 1.0) / h + 1.0)) * D1 + ) + elif self.config.algorithm_type == "dpmsolver": + # See https://huggingface.co/papers/2206.00927 for detailed derivations + if self.config.solver_type == "midpoint": + x_t = ( + (alpha_t / alpha_s0) * sample + - (sigma_t * (torch.exp(h) - 1.0)) * D0 + - 0.5 * (sigma_t * (torch.exp(h) - 1.0)) * D1 + ) + elif self.config.solver_type == "heun": + x_t = ( + (alpha_t / alpha_s0) * sample + - (sigma_t * (torch.exp(h) - 1.0)) * D0 + - (sigma_t * ((torch.exp(h) - 1.0) / h - 1.0)) * D1 + ) + elif self.config.algorithm_type == "sde-dpmsolver++": + assert noise is not None + if self.config.solver_type == "midpoint": + x_t = ( + (sigma_t / sigma_s0 * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * D0 + + 0.5 * (alpha_t * (1 - torch.exp(-2.0 * h))) * D1 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + elif self.config.solver_type == "heun": + x_t = ( + (sigma_t / sigma_s0 * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * D0 + + (alpha_t * ((1.0 - torch.exp(-2.0 * h)) / (-2.0 * h) + 1.0)) * D1 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + elif self.config.algorithm_type == "sde-dpmsolver": + assert noise is not None + if self.config.solver_type == "midpoint": + x_t = ( + (alpha_t / alpha_s0) * sample + - 2.0 * (sigma_t * (torch.exp(h) - 1.0)) * D0 + - (sigma_t * (torch.exp(h) - 1.0)) * D1 + + sigma_t * torch.sqrt(torch.exp(2 * h) - 1.0) * noise + ) + elif self.config.solver_type == "heun": + x_t = ( + (alpha_t / alpha_s0) * sample + - 2.0 * (sigma_t * (torch.exp(h) - 1.0)) * D0 + - 2.0 * (sigma_t * ((torch.exp(h) - 1.0) / h - 1.0)) * D1 + + sigma_t * torch.sqrt(torch.exp(2 * h) - 1.0) * noise + ) + return x_t + + def multistep_dpm_solver_third_order_update( + self, + model_output_list: List[torch.Tensor], + *args, + sample: torch.Tensor = None, + noise: Optional[torch.Tensor] = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the third-order multistep DPMSolver. + + Args: + model_output_list (`List[torch.Tensor]`): + The direct outputs from learned diffusion model at current and latter timesteps. + sample (`torch.Tensor`): + A current instance of a sample created by diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + + timestep_list = args[0] if len(args) > 0 else kwargs.pop("timestep_list", None) + prev_timestep = args[1] if len(args) > 1 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 2: + sample = args[2] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep_list is not None: + deprecate( + "timestep_list", + "1.0.0", + "Passing `timestep_list` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + sigma_t, sigma_s0, sigma_s1, sigma_s2 = ( + self.sigmas[self.step_index + 1], + self.sigmas[self.step_index], + self.sigmas[self.step_index - 1], + self.sigmas[self.step_index - 2], + ) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + alpha_s1, sigma_s1 = self._sigma_to_alpha_sigma_t(sigma_s1) + alpha_s2, sigma_s2 = self._sigma_to_alpha_sigma_t(sigma_s2) + + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s0 = torch.log(alpha_s0) - torch.log(sigma_s0) + lambda_s1 = torch.log(alpha_s1) - torch.log(sigma_s1) + lambda_s2 = torch.log(alpha_s2) - torch.log(sigma_s2) + + m0, m1, m2 = model_output_list[-1], model_output_list[-2], model_output_list[-3] + + h, h_0, h_1 = lambda_t - lambda_s0, lambda_s0 - lambda_s1, lambda_s1 - lambda_s2 + r0, r1 = h_0 / h, h_1 / h + D0 = m0 + D1_0, D1_1 = (1.0 / r0) * (m0 - m1), (1.0 / r1) * (m1 - m2) + D1 = D1_0 + (r0 / (r0 + r1)) * (D1_0 - D1_1) + D2 = (1.0 / (r0 + r1)) * (D1_0 - D1_1) + if self.config.algorithm_type == "dpmsolver++": + # See https://huggingface.co/papers/2206.00927 for detailed derivations + x_t = ( + (sigma_t / sigma_s0) * sample + - (alpha_t * (torch.exp(-h) - 1.0)) * D0 + + (alpha_t * ((torch.exp(-h) - 1.0) / h + 1.0)) * D1 + - (alpha_t * ((torch.exp(-h) - 1.0 + h) / h**2 - 0.5)) * D2 + ) + elif self.config.algorithm_type == "dpmsolver": + # See https://huggingface.co/papers/2206.00927 for detailed derivations + x_t = ( + (alpha_t / alpha_s0) * sample + - (sigma_t * (torch.exp(h) - 1.0)) * D0 + - (sigma_t * ((torch.exp(h) - 1.0) / h - 1.0)) * D1 + - (sigma_t * ((torch.exp(h) - 1.0 - h) / h**2 - 0.5)) * D2 + ) + elif self.config.algorithm_type == "sde-dpmsolver++": + assert noise is not None + x_t = ( + (sigma_t / sigma_s0 * torch.exp(-h)) * sample + + (alpha_t * (1.0 - torch.exp(-2.0 * h))) * D0 + + (alpha_t * ((1.0 - torch.exp(-2.0 * h)) / (-2.0 * h) + 1.0)) * D1 + + (alpha_t * ((1.0 - torch.exp(-2.0 * h) - 2.0 * h) / (2.0 * h) ** 2 - 0.5)) * D2 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + return x_t + + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + index_candidates = (schedule_timesteps == timestep).nonzero() + + if len(index_candidates) == 0: + step_index = len(self.timesteps) - 1 + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + elif len(index_candidates) > 1: + step_index = index_candidates[1].item() + else: + step_index = index_candidates[0].item() + + return step_index + + def _init_step_index(self, timestep): + """ + Initialize the step_index counter for the scheduler. + """ + + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.Tensor, + timestep: Union[int, torch.Tensor], + sample: torch.Tensor, + generator=None, + variance_noise: Optional[torch.Tensor] = None, + return_dict: bool = True, + ) -> Union[SchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the sample with + the multistep DPMSolver. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + variance_noise (`torch.Tensor`): + Alternative to generating noise with `generator` by directly providing the noise for the variance + itself. Useful for methods such as [`LEdits++`]. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_utils.SchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + if self.step_index is None: + self._init_step_index(timestep) + + # Improve numerical stability for small number of steps + lower_order_final = (self.step_index == len(self.timesteps) - 1) and ( + self.config.euler_at_final + or (self.config.lower_order_final and len(self.timesteps) < 15) + or self.config.final_sigmas_type == "zero" + ) + lower_order_second = ( + (self.step_index == len(self.timesteps) - 2) and self.config.lower_order_final and len(self.timesteps) < 15 + ) + + model_output = self.convert_model_output(model_output, sample=sample) + for i in range(self.config.solver_order - 1): + self.model_outputs[i] = self.model_outputs[i + 1] + self.model_outputs[-1] = model_output + + # Upcast to avoid precision issues when computing prev_sample + sample = sample.to(torch.float32) + if self.config.algorithm_type in ["sde-dpmsolver", "sde-dpmsolver++"] and variance_noise is None: + noise = randn_tensor( + model_output.shape, generator=generator, device=model_output.device, dtype=torch.float32 + ) + elif self.config.algorithm_type in ["sde-dpmsolver", "sde-dpmsolver++"]: + noise = variance_noise.to(device=model_output.device, dtype=torch.float32) + else: + noise = None + + if self.config.solver_order == 1 or self.lower_order_nums < 1 or lower_order_final: + prev_sample = self.dpm_solver_first_order_update(model_output, sample=sample, noise=noise) + elif self.config.solver_order == 2 or self.lower_order_nums < 2 or lower_order_second: + prev_sample = self.multistep_dpm_solver_second_order_update(self.model_outputs, sample=sample, noise=noise) + else: + prev_sample = self.multistep_dpm_solver_third_order_update(self.model_outputs, sample=sample, noise=noise) + + if self.lower_order_nums < self.config.solver_order: + self.lower_order_nums += 1 + + # Cast sample back to expected dtype + prev_sample = prev_sample.to(model_output.dtype) + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return (prev_sample,) + + return SchedulerOutput(prev_sample=prev_sample) + + def scale_model_input(self, sample: torch.Tensor, *args, **kwargs) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # begin_index is None when the scheduler is used for training or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + noisy_samples = alpha_t * original_samples + sigma_t * noise + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_multistep_flax.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_multistep_flax.py new file mode 100644 index 0000000000000000000000000000000000000000..10458431deda93b2b969f21dd2863f0ab69c1720 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_multistep_flax.py @@ -0,0 +1,645 @@ +# Copyright 2024 TSAIL Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/LuChengTHU/dpm-solver + +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import flax +import jax +import jax.numpy as jnp + +from ..configuration_utils import ConfigMixin, register_to_config +from .scheduling_utils_flax import ( + CommonSchedulerState, + FlaxKarrasDiffusionSchedulers, + FlaxSchedulerMixin, + FlaxSchedulerOutput, + add_noise_common, +) + + +@flax.struct.dataclass +class DPMSolverMultistepSchedulerState: + common: CommonSchedulerState + alpha_t: jnp.ndarray + sigma_t: jnp.ndarray + lambda_t: jnp.ndarray + + # setable values + init_noise_sigma: jnp.ndarray + timesteps: jnp.ndarray + num_inference_steps: Optional[int] = None + + # running values + model_outputs: Optional[jnp.ndarray] = None + lower_order_nums: Optional[jnp.int32] = None + prev_timestep: Optional[jnp.int32] = None + cur_sample: Optional[jnp.ndarray] = None + + @classmethod + def create( + cls, + common: CommonSchedulerState, + alpha_t: jnp.ndarray, + sigma_t: jnp.ndarray, + lambda_t: jnp.ndarray, + init_noise_sigma: jnp.ndarray, + timesteps: jnp.ndarray, + ): + return cls( + common=common, + alpha_t=alpha_t, + sigma_t=sigma_t, + lambda_t=lambda_t, + init_noise_sigma=init_noise_sigma, + timesteps=timesteps, + ) + + +@dataclass +class FlaxDPMSolverMultistepSchedulerOutput(FlaxSchedulerOutput): + state: DPMSolverMultistepSchedulerState + + +class FlaxDPMSolverMultistepScheduler(FlaxSchedulerMixin, ConfigMixin): + """ + DPM-Solver (and the improved version DPM-Solver++) is a fast dedicated high-order solver for diffusion ODEs with + the convergence order guarantee. Empirically, sampling by DPM-Solver with only 20 steps can generate high-quality + samples, and it can generate quite good samples even in only 10 steps. + + For more details, see the original paper: https://huggingface.co/papers/2206.00927 and + https://huggingface.co/papers/2211.01095 + + Currently, we support the multistep DPM-Solver for both noise prediction models and data prediction models. We + recommend to use `solver_order=2` for guided sampling, and `solver_order=3` for unconditional sampling. + + We also support the "dynamic thresholding" method in Imagen (https://huggingface.co/papers/2205.11487). For + pixel-space diffusion models, you can set both `algorithm_type="dpmsolver++"` and `thresholding=True` to use the + dynamic thresholding. Note that the thresholding method is unsuitable for latent-space diffusion models (such as + stable-diffusion). + + [`~ConfigMixin`] takes care of storing all config attributes that are passed in the scheduler's `__init__` + function, such as `num_train_timesteps`. They can be accessed via `scheduler.config.num_train_timesteps`. + [`SchedulerMixin`] provides general loading and saving functionality via the [`SchedulerMixin.save_pretrained`] and + [`~SchedulerMixin.from_pretrained`] functions. + + For more details, see the original paper: https://huggingface.co/papers/2206.00927 and + https://huggingface.co/papers/2211.01095 + + Args: + num_train_timesteps (`int`): number of diffusion steps used to train the model. + beta_start (`float`): the starting `beta` value of inference. + beta_end (`float`): the final `beta` value. + beta_schedule (`str`): + the beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, optional): + option to pass an array of betas directly to the constructor to bypass `beta_start`, `beta_end` etc. + solver_order (`int`, default `2`): + the order of DPM-Solver; can be `1` or `2` or `3`. We recommend to use `solver_order=2` for guided + sampling, and `solver_order=3` for unconditional sampling. + prediction_type (`str`, default `epsilon`): + indicates whether the model predicts the noise (epsilon), or the data / `x0`. One of `epsilon`, `sample`, + or `v-prediction`. + thresholding (`bool`, default `False`): + whether to use the "dynamic thresholding" method (introduced by Imagen, + https://huggingface.co/papers/2205.11487). For pixel-space diffusion models, you can set both + `algorithm_type=dpmsolver++` and `thresholding=True` to use the dynamic thresholding. Note that the + thresholding method is unsuitable for latent-space diffusion models (such as stable-diffusion). + dynamic_thresholding_ratio (`float`, default `0.995`): + the ratio for the dynamic thresholding method. Default is `0.995`, the same as Imagen + (https://huggingface.co/papers/2205.11487). + sample_max_value (`float`, default `1.0`): + the threshold value for dynamic thresholding. Valid only when `thresholding=True` and + `algorithm_type="dpmsolver++`. + algorithm_type (`str`, default `dpmsolver++`): + the algorithm type for the solver. Either `dpmsolver` or `dpmsolver++`. The `dpmsolver` type implements the + algorithms in https://huggingface.co/papers/2206.00927, and the `dpmsolver++` type implements the + algorithms in https://huggingface.co/papers/2211.01095. We recommend to use `dpmsolver++` with + `solver_order=2` for guided sampling (e.g. stable-diffusion). + solver_type (`str`, default `midpoint`): + the solver type for the second-order solver. Either `midpoint` or `heun`. The solver type slightly affects + the sample quality, especially for small number of steps. We empirically find that `midpoint` solvers are + slightly better, so we recommend to use the `midpoint` type. + lower_order_final (`bool`, default `True`): + whether to use lower-order solvers in the final steps. Only valid for < 15 inference steps. We empirically + find this trick can stabilize the sampling of DPM-Solver for steps < 15, especially for steps <= 10. + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + dtype (`jnp.dtype`, *optional*, defaults to `jnp.float32`): + the `dtype` used for params and computation. + """ + + _compatibles = [e.name for e in FlaxKarrasDiffusionSchedulers] + + dtype: jnp.dtype + + @property + def has_state(self): + return True + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[jnp.ndarray] = None, + solver_order: int = 2, + prediction_type: str = "epsilon", + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + sample_max_value: float = 1.0, + algorithm_type: str = "dpmsolver++", + solver_type: str = "midpoint", + lower_order_final: bool = True, + timestep_spacing: str = "linspace", + dtype: jnp.dtype = jnp.float32, + ): + self.dtype = dtype + + def create_state(self, common: Optional[CommonSchedulerState] = None) -> DPMSolverMultistepSchedulerState: + if common is None: + common = CommonSchedulerState.create(self) + + # Currently we only support VP-type noise schedule + alpha_t = jnp.sqrt(common.alphas_cumprod) + sigma_t = jnp.sqrt(1 - common.alphas_cumprod) + lambda_t = jnp.log(alpha_t) - jnp.log(sigma_t) + + # settings for DPM-Solver + if self.config.algorithm_type not in ["dpmsolver", "dpmsolver++"]: + raise NotImplementedError(f"{self.config.algorithm_type} is not implemented for {self.__class__}") + if self.config.solver_type not in ["midpoint", "heun"]: + raise NotImplementedError(f"{self.config.solver_type} is not implemented for {self.__class__}") + + # standard deviation of the initial noise distribution + init_noise_sigma = jnp.array(1.0, dtype=self.dtype) + + timesteps = jnp.arange(0, self.config.num_train_timesteps).round()[::-1] + + return DPMSolverMultistepSchedulerState.create( + common=common, + alpha_t=alpha_t, + sigma_t=sigma_t, + lambda_t=lambda_t, + init_noise_sigma=init_noise_sigma, + timesteps=timesteps, + ) + + def set_timesteps( + self, state: DPMSolverMultistepSchedulerState, num_inference_steps: int, shape: Tuple + ) -> DPMSolverMultistepSchedulerState: + """ + Sets the discrete timesteps used for the diffusion chain. Supporting function to be run before inference. + + Args: + state (`DPMSolverMultistepSchedulerState`): + the `FlaxDPMSolverMultistepScheduler` state data class instance. + num_inference_steps (`int`): + the number of diffusion steps used when generating samples with a pre-trained model. + shape (`Tuple`): + the shape of the samples to be generated. + """ + last_timestep = self.config.num_train_timesteps + if self.config.timestep_spacing == "linspace": + timesteps = ( + jnp.linspace(0, last_timestep - 1, num_inference_steps + 1).round()[::-1][:-1].astype(jnp.int32) + ) + elif self.config.timestep_spacing == "leading": + step_ratio = last_timestep // (num_inference_steps + 1) + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = ( + (jnp.arange(0, num_inference_steps + 1) * step_ratio).round()[::-1][:-1].copy().astype(jnp.int32) + ) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = jnp.arange(last_timestep, 0, -step_ratio).round().copy().astype(jnp.int32) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + # initial running values + + model_outputs = jnp.zeros((self.config.solver_order,) + shape, dtype=self.dtype) + lower_order_nums = jnp.int32(0) + prev_timestep = jnp.int32(-1) + cur_sample = jnp.zeros(shape, dtype=self.dtype) + + return state.replace( + num_inference_steps=num_inference_steps, + timesteps=timesteps, + model_outputs=model_outputs, + lower_order_nums=lower_order_nums, + prev_timestep=prev_timestep, + cur_sample=cur_sample, + ) + + def convert_model_output( + self, + state: DPMSolverMultistepSchedulerState, + model_output: jnp.ndarray, + timestep: int, + sample: jnp.ndarray, + ) -> jnp.ndarray: + """ + Convert the model output to the corresponding type that the algorithm (DPM-Solver / DPM-Solver++) needs. + + DPM-Solver is designed to discretize an integral of the noise prediction model, and DPM-Solver++ is designed to + discretize an integral of the data prediction model. So we need to first convert the model output to the + corresponding type to match the algorithm. + + Note that the algorithm type and the model type is decoupled. That is to say, we can use either DPM-Solver or + DPM-Solver++ for both noise prediction model and data prediction model. + + Args: + model_output (`jnp.ndarray`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + + Returns: + `jnp.ndarray`: the converted model output. + """ + # DPM-Solver++ needs to solve an integral of the data prediction model. + if self.config.algorithm_type == "dpmsolver++": + if self.config.prediction_type == "epsilon": + alpha_t, sigma_t = state.alpha_t[timestep], state.sigma_t[timestep] + x0_pred = (sample - sigma_t * model_output) / alpha_t + elif self.config.prediction_type == "sample": + x0_pred = model_output + elif self.config.prediction_type == "v_prediction": + alpha_t, sigma_t = state.alpha_t[timestep], state.sigma_t[timestep] + x0_pred = alpha_t * sample - sigma_t * model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, " + " or `v_prediction` for the FlaxDPMSolverMultistepScheduler." + ) + + if self.config.thresholding: + # Dynamic thresholding in https://huggingface.co/papers/2205.11487 + dynamic_max_val = jnp.percentile( + jnp.abs(x0_pred), self.config.dynamic_thresholding_ratio, axis=tuple(range(1, x0_pred.ndim)) + ) + dynamic_max_val = jnp.maximum( + dynamic_max_val, self.config.sample_max_value * jnp.ones_like(dynamic_max_val) + ) + x0_pred = jnp.clip(x0_pred, -dynamic_max_val, dynamic_max_val) / dynamic_max_val + return x0_pred + # DPM-Solver needs to solve an integral of the noise prediction model. + elif self.config.algorithm_type == "dpmsolver": + if self.config.prediction_type == "epsilon": + return model_output + elif self.config.prediction_type == "sample": + alpha_t, sigma_t = state.alpha_t[timestep], state.sigma_t[timestep] + epsilon = (sample - alpha_t * model_output) / sigma_t + return epsilon + elif self.config.prediction_type == "v_prediction": + alpha_t, sigma_t = state.alpha_t[timestep], state.sigma_t[timestep] + epsilon = alpha_t * model_output + sigma_t * sample + return epsilon + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, " + " or `v_prediction` for the FlaxDPMSolverMultistepScheduler." + ) + + def dpm_solver_first_order_update( + self, + state: DPMSolverMultistepSchedulerState, + model_output: jnp.ndarray, + timestep: int, + prev_timestep: int, + sample: jnp.ndarray, + ) -> jnp.ndarray: + """ + One step for the first-order DPM-Solver (equivalent to DDIM). + + See https://huggingface.co/papers/2206.00927 for the detailed derivation. + + Args: + model_output (`jnp.ndarray`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + prev_timestep (`int`): previous discrete timestep in the diffusion chain. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + + Returns: + `jnp.ndarray`: the sample tensor at the previous timestep. + """ + t, s0 = prev_timestep, timestep + m0 = model_output + lambda_t, lambda_s = state.lambda_t[t], state.lambda_t[s0] + alpha_t, alpha_s = state.alpha_t[t], state.alpha_t[s0] + sigma_t, sigma_s = state.sigma_t[t], state.sigma_t[s0] + h = lambda_t - lambda_s + if self.config.algorithm_type == "dpmsolver++": + x_t = (sigma_t / sigma_s) * sample - (alpha_t * (jnp.exp(-h) - 1.0)) * m0 + elif self.config.algorithm_type == "dpmsolver": + x_t = (alpha_t / alpha_s) * sample - (sigma_t * (jnp.exp(h) - 1.0)) * m0 + return x_t + + def multistep_dpm_solver_second_order_update( + self, + state: DPMSolverMultistepSchedulerState, + model_output_list: jnp.ndarray, + timestep_list: List[int], + prev_timestep: int, + sample: jnp.ndarray, + ) -> jnp.ndarray: + """ + One step for the second-order multistep DPM-Solver. + + Args: + model_output_list (`List[jnp.ndarray]`): + direct outputs from learned diffusion model at current and latter timesteps. + timestep (`int`): current and latter discrete timestep in the diffusion chain. + prev_timestep (`int`): previous discrete timestep in the diffusion chain. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + + Returns: + `jnp.ndarray`: the sample tensor at the previous timestep. + """ + t, s0, s1 = prev_timestep, timestep_list[-1], timestep_list[-2] + m0, m1 = model_output_list[-1], model_output_list[-2] + lambda_t, lambda_s0, lambda_s1 = state.lambda_t[t], state.lambda_t[s0], state.lambda_t[s1] + alpha_t, alpha_s0 = state.alpha_t[t], state.alpha_t[s0] + sigma_t, sigma_s0 = state.sigma_t[t], state.sigma_t[s0] + h, h_0 = lambda_t - lambda_s0, lambda_s0 - lambda_s1 + r0 = h_0 / h + D0, D1 = m0, (1.0 / r0) * (m0 - m1) + if self.config.algorithm_type == "dpmsolver++": + # See https://huggingface.co/papers/2211.01095 for detailed derivations + if self.config.solver_type == "midpoint": + x_t = ( + (sigma_t / sigma_s0) * sample + - (alpha_t * (jnp.exp(-h) - 1.0)) * D0 + - 0.5 * (alpha_t * (jnp.exp(-h) - 1.0)) * D1 + ) + elif self.config.solver_type == "heun": + x_t = ( + (sigma_t / sigma_s0) * sample + - (alpha_t * (jnp.exp(-h) - 1.0)) * D0 + + (alpha_t * ((jnp.exp(-h) - 1.0) / h + 1.0)) * D1 + ) + elif self.config.algorithm_type == "dpmsolver": + # See https://huggingface.co/papers/2206.00927 for detailed derivations + if self.config.solver_type == "midpoint": + x_t = ( + (alpha_t / alpha_s0) * sample + - (sigma_t * (jnp.exp(h) - 1.0)) * D0 + - 0.5 * (sigma_t * (jnp.exp(h) - 1.0)) * D1 + ) + elif self.config.solver_type == "heun": + x_t = ( + (alpha_t / alpha_s0) * sample + - (sigma_t * (jnp.exp(h) - 1.0)) * D0 + - (sigma_t * ((jnp.exp(h) - 1.0) / h - 1.0)) * D1 + ) + return x_t + + def multistep_dpm_solver_third_order_update( + self, + state: DPMSolverMultistepSchedulerState, + model_output_list: jnp.ndarray, + timestep_list: List[int], + prev_timestep: int, + sample: jnp.ndarray, + ) -> jnp.ndarray: + """ + One step for the third-order multistep DPM-Solver. + + Args: + model_output_list (`List[jnp.ndarray]`): + direct outputs from learned diffusion model at current and latter timesteps. + timestep (`int`): current and latter discrete timestep in the diffusion chain. + prev_timestep (`int`): previous discrete timestep in the diffusion chain. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + + Returns: + `jnp.ndarray`: the sample tensor at the previous timestep. + """ + t, s0, s1, s2 = prev_timestep, timestep_list[-1], timestep_list[-2], timestep_list[-3] + m0, m1, m2 = model_output_list[-1], model_output_list[-2], model_output_list[-3] + lambda_t, lambda_s0, lambda_s1, lambda_s2 = ( + state.lambda_t[t], + state.lambda_t[s0], + state.lambda_t[s1], + state.lambda_t[s2], + ) + alpha_t, alpha_s0 = state.alpha_t[t], state.alpha_t[s0] + sigma_t, sigma_s0 = state.sigma_t[t], state.sigma_t[s0] + h, h_0, h_1 = lambda_t - lambda_s0, lambda_s0 - lambda_s1, lambda_s1 - lambda_s2 + r0, r1 = h_0 / h, h_1 / h + D0 = m0 + D1_0, D1_1 = (1.0 / r0) * (m0 - m1), (1.0 / r1) * (m1 - m2) + D1 = D1_0 + (r0 / (r0 + r1)) * (D1_0 - D1_1) + D2 = (1.0 / (r0 + r1)) * (D1_0 - D1_1) + if self.config.algorithm_type == "dpmsolver++": + # See https://huggingface.co/papers/2206.00927 for detailed derivations + x_t = ( + (sigma_t / sigma_s0) * sample + - (alpha_t * (jnp.exp(-h) - 1.0)) * D0 + + (alpha_t * ((jnp.exp(-h) - 1.0) / h + 1.0)) * D1 + - (alpha_t * ((jnp.exp(-h) - 1.0 + h) / h**2 - 0.5)) * D2 + ) + elif self.config.algorithm_type == "dpmsolver": + # See https://huggingface.co/papers/2206.00927 for detailed derivations + x_t = ( + (alpha_t / alpha_s0) * sample + - (sigma_t * (jnp.exp(h) - 1.0)) * D0 + - (sigma_t * ((jnp.exp(h) - 1.0) / h - 1.0)) * D1 + - (sigma_t * ((jnp.exp(h) - 1.0 - h) / h**2 - 0.5)) * D2 + ) + return x_t + + def step( + self, + state: DPMSolverMultistepSchedulerState, + model_output: jnp.ndarray, + timestep: int, + sample: jnp.ndarray, + return_dict: bool = True, + ) -> Union[FlaxDPMSolverMultistepSchedulerOutput, Tuple]: + """ + Predict the sample at the previous timestep by DPM-Solver. Core function to propagate the diffusion process + from the learned model outputs (most often the predicted noise). + + Args: + state (`DPMSolverMultistepSchedulerState`): + the `FlaxDPMSolverMultistepScheduler` state data class instance. + model_output (`jnp.ndarray`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + return_dict (`bool`): option for returning tuple rather than FlaxDPMSolverMultistepSchedulerOutput class + + Returns: + [`FlaxDPMSolverMultistepSchedulerOutput`] or `tuple`: [`FlaxDPMSolverMultistepSchedulerOutput`] if + `return_dict` is True, otherwise a `tuple`. When returning a tuple, the first element is the sample tensor. + + """ + if state.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + (step_index,) = jnp.where(state.timesteps == timestep, size=1) + step_index = step_index[0] + + prev_timestep = jax.lax.select(step_index == len(state.timesteps) - 1, 0, state.timesteps[step_index + 1]) + + model_output = self.convert_model_output(state, model_output, timestep, sample) + + model_outputs_new = jnp.roll(state.model_outputs, -1, axis=0) + model_outputs_new = model_outputs_new.at[-1].set(model_output) + state = state.replace( + model_outputs=model_outputs_new, + prev_timestep=prev_timestep, + cur_sample=sample, + ) + + def step_1(state: DPMSolverMultistepSchedulerState) -> jnp.ndarray: + return self.dpm_solver_first_order_update( + state, + state.model_outputs[-1], + state.timesteps[step_index], + state.prev_timestep, + state.cur_sample, + ) + + def step_23(state: DPMSolverMultistepSchedulerState) -> jnp.ndarray: + def step_2(state: DPMSolverMultistepSchedulerState) -> jnp.ndarray: + timestep_list = jnp.array([state.timesteps[step_index - 1], state.timesteps[step_index]]) + return self.multistep_dpm_solver_second_order_update( + state, + state.model_outputs, + timestep_list, + state.prev_timestep, + state.cur_sample, + ) + + def step_3(state: DPMSolverMultistepSchedulerState) -> jnp.ndarray: + timestep_list = jnp.array( + [ + state.timesteps[step_index - 2], + state.timesteps[step_index - 1], + state.timesteps[step_index], + ] + ) + return self.multistep_dpm_solver_third_order_update( + state, + state.model_outputs, + timestep_list, + state.prev_timestep, + state.cur_sample, + ) + + step_2_output = step_2(state) + step_3_output = step_3(state) + + if self.config.solver_order == 2: + return step_2_output + elif self.config.lower_order_final and len(state.timesteps) < 15: + return jax.lax.select( + state.lower_order_nums < 2, + step_2_output, + jax.lax.select( + step_index == len(state.timesteps) - 2, + step_2_output, + step_3_output, + ), + ) + else: + return jax.lax.select( + state.lower_order_nums < 2, + step_2_output, + step_3_output, + ) + + step_1_output = step_1(state) + step_23_output = step_23(state) + + if self.config.solver_order == 1: + prev_sample = step_1_output + + elif self.config.lower_order_final and len(state.timesteps) < 15: + prev_sample = jax.lax.select( + state.lower_order_nums < 1, + step_1_output, + jax.lax.select( + step_index == len(state.timesteps) - 1, + step_1_output, + step_23_output, + ), + ) + + else: + prev_sample = jax.lax.select( + state.lower_order_nums < 1, + step_1_output, + step_23_output, + ) + + state = state.replace( + lower_order_nums=jnp.minimum(state.lower_order_nums + 1, self.config.solver_order), + ) + + if not return_dict: + return (prev_sample, state) + + return FlaxDPMSolverMultistepSchedulerOutput(prev_sample=prev_sample, state=state) + + def scale_model_input( + self, state: DPMSolverMultistepSchedulerState, sample: jnp.ndarray, timestep: Optional[int] = None + ) -> jnp.ndarray: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + state (`DPMSolverMultistepSchedulerState`): + the `FlaxDPMSolverMultistepScheduler` state data class instance. + sample (`jnp.ndarray`): input sample + timestep (`int`, optional): current timestep + + Returns: + `jnp.ndarray`: scaled input sample + """ + return sample + + def add_noise( + self, + state: DPMSolverMultistepSchedulerState, + original_samples: jnp.ndarray, + noise: jnp.ndarray, + timesteps: jnp.ndarray, + ) -> jnp.ndarray: + return add_noise_common(state.common, original_samples, noise, timesteps) + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_multistep_inverse.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_multistep_inverse.py new file mode 100644 index 0000000000000000000000000000000000000000..29da9fb0d5a835e508ce3d049464a1a395c8c6ac --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_multistep_inverse.py @@ -0,0 +1,1027 @@ +# Copyright 2024 TSAIL Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/LuChengTHU/dpm-solver + +import math +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import deprecate, is_scipy_available +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin, SchedulerOutput + + +if is_scipy_available(): + import scipy.stats + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +class DPMSolverMultistepInverseScheduler(SchedulerMixin, ConfigMixin): + """ + `DPMSolverMultistepInverseScheduler` is the reverse scheduler of [`DPMSolverMultistepScheduler`]. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + solver_order (`int`, defaults to 2): + The DPMSolver order which can be `1` or `2` or `3`. It is recommended to use `solver_order=2` for guided + sampling, and `solver_order=3` for unconditional sampling. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + thresholding (`bool`, defaults to `False`): + Whether to use the "dynamic thresholding" method. This is unsuitable for latent-space diffusion models such + as Stable Diffusion. + dynamic_thresholding_ratio (`float`, defaults to 0.995): + The ratio for the dynamic thresholding method. Valid only when `thresholding=True`. + sample_max_value (`float`, defaults to 1.0): + The threshold value for dynamic thresholding. Valid only when `thresholding=True` and + `algorithm_type="dpmsolver++"`. + algorithm_type (`str`, defaults to `dpmsolver++`): + Algorithm type for the solver; can be `dpmsolver`, `dpmsolver++`, `sde-dpmsolver` or `sde-dpmsolver++`. The + `dpmsolver` type implements the algorithms in the [DPMSolver](https://huggingface.co/papers/2206.00927) + paper, and the `dpmsolver++` type implements the algorithms in the + [DPMSolver++](https://huggingface.co/papers/2211.01095) paper. It is recommended to use `dpmsolver++` or + `sde-dpmsolver++` with `solver_order=2` for guided sampling like in Stable Diffusion. + solver_type (`str`, defaults to `midpoint`): + Solver type for the second-order solver; can be `midpoint` or `heun`. The solver type slightly affects the + sample quality, especially for a small number of steps. It is recommended to use `midpoint` solvers. + lower_order_final (`bool`, defaults to `True`): + Whether to use lower-order solvers in the final steps. Only valid for < 15 inference steps. This can + stabilize the sampling of DPMSolver for steps < 15, especially for steps <= 10. + euler_at_final (`bool`, defaults to `False`): + Whether to use Euler's method in the final step. It is a trade-off between numerical stability and detail + richness. This can stabilize the sampling of the SDE variant of DPMSolver for small number of inference + steps, but sometimes may result in blurring. + use_karras_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use Karras sigmas for step sizes in the noise schedule during the sampling process. If `True`, + the sigmas are determined according to a sequence of noise levels {σi}. + use_exponential_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use exponential sigmas for step sizes in the noise schedule during the sampling process. + use_beta_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use beta sigmas for step sizes in the noise schedule during the sampling process. Refer to [Beta + Sampling is All You Need](https://huggingface.co/papers/2407.12173) for more information. + lambda_min_clipped (`float`, defaults to `-inf`): + Clipping threshold for the minimum value of `lambda(t)` for numerical stability. This is critical for the + cosine (`squaredcos_cap_v2`) noise schedule. + variance_type (`str`, *optional*): + Set to "learned" or "learned_range" for diffusion models that predict variance. If set, the model's output + contains the predicted Gaussian variance. + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + solver_order: int = 2, + prediction_type: str = "epsilon", + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + sample_max_value: float = 1.0, + algorithm_type: str = "dpmsolver++", + solver_type: str = "midpoint", + lower_order_final: bool = True, + euler_at_final: bool = False, + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + use_flow_sigmas: Optional[bool] = False, + flow_shift: Optional[float] = 1.0, + lambda_min_clipped: float = -float("inf"), + variance_type: Optional[str] = None, + timestep_spacing: str = "linspace", + steps_offset: int = 0, + ): + if self.config.use_beta_sigmas and not is_scipy_available(): + raise ImportError("Make sure to install scipy if you want to use beta sigmas.") + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if algorithm_type in ["dpmsolver", "sde-dpmsolver"]: + deprecation_message = f"algorithm_type {algorithm_type} is deprecated and will be removed in a future version. Choose from `dpmsolver++` or `sde-dpmsolver++` instead" + deprecate("algorithm_types dpmsolver and sde-dpmsolver", "1.0.0", deprecation_message) + + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + # Currently we only support VP-type noise schedule + self.alpha_t = torch.sqrt(self.alphas_cumprod) + self.sigma_t = torch.sqrt(1 - self.alphas_cumprod) + self.lambda_t = torch.log(self.alpha_t) - torch.log(self.sigma_t) + self.sigmas = ((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5 + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # settings for DPM-Solver + if algorithm_type not in ["dpmsolver", "dpmsolver++", "sde-dpmsolver", "sde-dpmsolver++"]: + if algorithm_type == "deis": + self.register_to_config(algorithm_type="dpmsolver++") + else: + raise NotImplementedError(f"{algorithm_type} is not implemented for {self.__class__}") + + if solver_type not in ["midpoint", "heun"]: + if solver_type in ["logrho", "bh1", "bh2"]: + self.register_to_config(solver_type="midpoint") + else: + raise NotImplementedError(f"{solver_type} is not implemented for {self.__class__}") + + # setable values + self.num_inference_steps = None + timesteps = np.linspace(0, num_train_timesteps - 1, num_train_timesteps, dtype=np.float32).copy() + self.timesteps = torch.from_numpy(timesteps) + self.model_outputs = [None] * solver_order + self.lower_order_nums = 0 + self._step_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + self.use_karras_sigmas = use_karras_sigmas + self.use_exponential_sigmas = use_exponential_sigmas + self.use_beta_sigmas = use_beta_sigmas + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + def set_timesteps(self, num_inference_steps: int = None, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + # Clipping the minimum of all lambda(t) for numerical stability. + # This is critical for cosine (squaredcos_cap_v2) noise schedule. + clipped_idx = torch.searchsorted(torch.flip(self.lambda_t, [0]), self.config.lambda_min_clipped).item() + self.noisiest_timestep = self.config.num_train_timesteps - 1 - clipped_idx + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = ( + np.linspace(0, self.noisiest_timestep, num_inference_steps + 1).round()[:-1].copy().astype(np.int64) + ) + elif self.config.timestep_spacing == "leading": + step_ratio = (self.noisiest_timestep + 1) // (num_inference_steps + 1) + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps + 1) * step_ratio).round()[:-1].copy().astype(np.int64) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = np.arange(self.noisiest_timestep + 1, 0, -step_ratio).round()[::-1].copy().astype(np.int64) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', " + "'leading' or 'trailing'." + ) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + log_sigmas = np.log(sigmas) + + if self.config.use_karras_sigmas: + sigmas = self._convert_to_karras(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]).round() + timesteps = timesteps.copy().astype(np.int64) + sigmas = np.concatenate([sigmas, sigmas[-1:]]).astype(np.float32) + elif self.config.use_exponential_sigmas: + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + sigmas = np.concatenate([sigmas, sigmas[-1:]]).astype(np.float32) + elif self.config.use_beta_sigmas: + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + sigmas = np.concatenate([sigmas, sigmas[-1:]]).astype(np.float32) + elif self.config.use_flow_sigmas: + alphas = np.linspace(1, 1 / self.config.num_train_timesteps, num_inference_steps + 1) + sigmas = 1.0 - alphas + sigmas = np.flip(self.config.flow_shift * sigmas / (1 + (self.config.flow_shift - 1) * sigmas))[:-1].copy() + timesteps = (sigmas * self.config.num_train_timesteps).copy() + sigmas = np.concatenate([sigmas, sigmas[-1:]]).astype(np.float32) + else: + sigmas = np.interp(timesteps, np.arange(0, len(sigmas)), sigmas) + sigma_max = ( + (1 - self.alphas_cumprod[self.noisiest_timestep]) / self.alphas_cumprod[self.noisiest_timestep] + ) ** 0.5 + sigmas = np.concatenate([sigmas, [sigma_max]]).astype(np.float32) + + self.sigmas = torch.from_numpy(sigmas) + + # when num_inference_steps == num_train_timesteps, we can end up with + # duplicates in timesteps. + _, unique_indices = np.unique(timesteps, return_index=True) + timesteps = timesteps[np.sort(unique_indices)] + + self.timesteps = torch.from_numpy(timesteps).to(device=device, dtype=torch.int64) + + self.num_inference_steps = len(timesteps) + + self.model_outputs = [ + None, + ] * self.config.solver_order + self.lower_order_nums = 0 + + # add an index counter for schedulers that allow duplicated timesteps + self._step_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler._threshold_sample + def _threshold_sample(self, sample: torch.Tensor) -> torch.Tensor: + """ + "Dynamic thresholding: At each sampling step we set s to a certain percentile absolute pixel value in xt0 (the + prediction of x_0 at timestep t), and if s > 1, then we threshold xt0 to the range [-s, s] and then divide by + s. Dynamic thresholding pushes saturated pixels (those near -1 and 1) inwards, thereby actively preventing + pixels from saturation at each step. We find that dynamic thresholding results in significantly better + photorealism as well as better image-text alignment, especially when using very large guidance weights." + + https://huggingface.co/papers/2205.11487 + """ + dtype = sample.dtype + batch_size, channels, *remaining_dims = sample.shape + + if dtype not in (torch.float32, torch.float64): + sample = sample.float() # upcast for quantile calculation, and clamp not implemented for cpu half + + # Flatten sample for doing quantile calculation along each image + sample = sample.reshape(batch_size, channels * np.prod(remaining_dims)) + + abs_sample = sample.abs() # "a certain percentile absolute pixel value" + + s = torch.quantile(abs_sample, self.config.dynamic_thresholding_ratio, dim=1) + s = torch.clamp( + s, min=1, max=self.config.sample_max_value + ) # When clamped to min=1, equivalent to standard clipping to [-1, 1] + s = s.unsqueeze(1) # (batch_size, 1) because clamp will broadcast along dim=0 + sample = torch.clamp(sample, -s, s) / s # "we threshold xt0 to the range [-s, s] and then divide by s" + + sample = sample.reshape(batch_size, channels, *remaining_dims) + sample = sample.to(dtype) + + return sample + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._sigma_to_t + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler._sigma_to_alpha_sigma_t + def _sigma_to_alpha_sigma_t(self, sigma): + if self.config.use_flow_sigmas: + alpha_t = 1 - sigma + sigma_t = sigma + else: + alpha_t = 1 / ((sigma**2 + 1) ** 0.5) + sigma_t = sigma * alpha_t + + return alpha_t, sigma_t + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_karras + def _convert_to_karras(self, in_sigmas: torch.Tensor, num_inference_steps) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_exponential + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_beta + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.convert_model_output + def convert_model_output( + self, + model_output: torch.Tensor, + *args, + sample: torch.Tensor = None, + **kwargs, + ) -> torch.Tensor: + """ + Convert the model output to the corresponding type the DPMSolver/DPMSolver++ algorithm needs. DPM-Solver is + designed to discretize an integral of the noise prediction model, and DPM-Solver++ is designed to discretize an + integral of the data prediction model. + + + + The algorithm and model type are decoupled. You can use either DPMSolver or DPMSolver++ for both noise + prediction and data prediction models. + + + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The converted model output. + """ + timestep = args[0] if len(args) > 0 else kwargs.pop("timestep", None) + if sample is None: + if len(args) > 1: + sample = args[1] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep is not None: + deprecate( + "timesteps", + "1.0.0", + "Passing `timesteps` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + # DPM-Solver++ needs to solve an integral of the data prediction model. + if self.config.algorithm_type in ["dpmsolver++", "sde-dpmsolver++"]: + if self.config.prediction_type == "epsilon": + # DPM-Solver and DPM-Solver++ only need the "mean" output. + if self.config.variance_type in ["learned", "learned_range"]: + model_output = model_output[:, :3] + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + x0_pred = (sample - sigma_t * model_output) / alpha_t + elif self.config.prediction_type == "sample": + x0_pred = model_output + elif self.config.prediction_type == "v_prediction": + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + x0_pred = alpha_t * sample - sigma_t * model_output + elif self.config.prediction_type == "flow_prediction": + sigma_t = self.sigmas[self.step_index] + x0_pred = sample - sigma_t * model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, " + "`v_prediction`, or `flow_prediction` for the DPMSolverMultistepScheduler." + ) + + if self.config.thresholding: + x0_pred = self._threshold_sample(x0_pred) + + return x0_pred + + # DPM-Solver needs to solve an integral of the noise prediction model. + elif self.config.algorithm_type in ["dpmsolver", "sde-dpmsolver"]: + if self.config.prediction_type == "epsilon": + # DPM-Solver and DPM-Solver++ only need the "mean" output. + if self.config.variance_type in ["learned", "learned_range"]: + epsilon = model_output[:, :3] + else: + epsilon = model_output + elif self.config.prediction_type == "sample": + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + epsilon = (sample - alpha_t * model_output) / sigma_t + elif self.config.prediction_type == "v_prediction": + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + epsilon = alpha_t * model_output + sigma_t * sample + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, or" + " `v_prediction` for the DPMSolverMultistepScheduler." + ) + + if self.config.thresholding: + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + x0_pred = (sample - sigma_t * epsilon) / alpha_t + x0_pred = self._threshold_sample(x0_pred) + epsilon = (sample - alpha_t * x0_pred) / sigma_t + + return epsilon + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.dpm_solver_first_order_update + def dpm_solver_first_order_update( + self, + model_output: torch.Tensor, + *args, + sample: torch.Tensor = None, + noise: Optional[torch.Tensor] = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the first-order DPMSolver (equivalent to DDIM). + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + timestep = args[0] if len(args) > 0 else kwargs.pop("timestep", None) + prev_timestep = args[1] if len(args) > 1 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 2: + sample = args[2] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep is not None: + deprecate( + "timesteps", + "1.0.0", + "Passing `timesteps` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + sigma_t, sigma_s = self.sigmas[self.step_index + 1], self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s, sigma_s = self._sigma_to_alpha_sigma_t(sigma_s) + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s = torch.log(alpha_s) - torch.log(sigma_s) + + h = lambda_t - lambda_s + if self.config.algorithm_type == "dpmsolver++": + x_t = (sigma_t / sigma_s) * sample - (alpha_t * (torch.exp(-h) - 1.0)) * model_output + elif self.config.algorithm_type == "dpmsolver": + x_t = (alpha_t / alpha_s) * sample - (sigma_t * (torch.exp(h) - 1.0)) * model_output + elif self.config.algorithm_type == "sde-dpmsolver++": + assert noise is not None + x_t = ( + (sigma_t / sigma_s * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * model_output + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + elif self.config.algorithm_type == "sde-dpmsolver": + assert noise is not None + x_t = ( + (alpha_t / alpha_s) * sample + - 2.0 * (sigma_t * (torch.exp(h) - 1.0)) * model_output + + sigma_t * torch.sqrt(torch.exp(2 * h) - 1.0) * noise + ) + return x_t + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.multistep_dpm_solver_second_order_update + def multistep_dpm_solver_second_order_update( + self, + model_output_list: List[torch.Tensor], + *args, + sample: torch.Tensor = None, + noise: Optional[torch.Tensor] = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the second-order multistep DPMSolver. + + Args: + model_output_list (`List[torch.Tensor]`): + The direct outputs from learned diffusion model at current and latter timesteps. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + timestep_list = args[0] if len(args) > 0 else kwargs.pop("timestep_list", None) + prev_timestep = args[1] if len(args) > 1 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 2: + sample = args[2] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep_list is not None: + deprecate( + "timestep_list", + "1.0.0", + "Passing `timestep_list` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + sigma_t, sigma_s0, sigma_s1 = ( + self.sigmas[self.step_index + 1], + self.sigmas[self.step_index], + self.sigmas[self.step_index - 1], + ) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + alpha_s1, sigma_s1 = self._sigma_to_alpha_sigma_t(sigma_s1) + + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s0 = torch.log(alpha_s0) - torch.log(sigma_s0) + lambda_s1 = torch.log(alpha_s1) - torch.log(sigma_s1) + + m0, m1 = model_output_list[-1], model_output_list[-2] + + h, h_0 = lambda_t - lambda_s0, lambda_s0 - lambda_s1 + r0 = h_0 / h + D0, D1 = m0, (1.0 / r0) * (m0 - m1) + if self.config.algorithm_type == "dpmsolver++": + # See https://huggingface.co/papers/2211.01095 for detailed derivations + if self.config.solver_type == "midpoint": + x_t = ( + (sigma_t / sigma_s0) * sample + - (alpha_t * (torch.exp(-h) - 1.0)) * D0 + - 0.5 * (alpha_t * (torch.exp(-h) - 1.0)) * D1 + ) + elif self.config.solver_type == "heun": + x_t = ( + (sigma_t / sigma_s0) * sample + - (alpha_t * (torch.exp(-h) - 1.0)) * D0 + + (alpha_t * ((torch.exp(-h) - 1.0) / h + 1.0)) * D1 + ) + elif self.config.algorithm_type == "dpmsolver": + # See https://huggingface.co/papers/2206.00927 for detailed derivations + if self.config.solver_type == "midpoint": + x_t = ( + (alpha_t / alpha_s0) * sample + - (sigma_t * (torch.exp(h) - 1.0)) * D0 + - 0.5 * (sigma_t * (torch.exp(h) - 1.0)) * D1 + ) + elif self.config.solver_type == "heun": + x_t = ( + (alpha_t / alpha_s0) * sample + - (sigma_t * (torch.exp(h) - 1.0)) * D0 + - (sigma_t * ((torch.exp(h) - 1.0) / h - 1.0)) * D1 + ) + elif self.config.algorithm_type == "sde-dpmsolver++": + assert noise is not None + if self.config.solver_type == "midpoint": + x_t = ( + (sigma_t / sigma_s0 * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * D0 + + 0.5 * (alpha_t * (1 - torch.exp(-2.0 * h))) * D1 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + elif self.config.solver_type == "heun": + x_t = ( + (sigma_t / sigma_s0 * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * D0 + + (alpha_t * ((1.0 - torch.exp(-2.0 * h)) / (-2.0 * h) + 1.0)) * D1 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + elif self.config.algorithm_type == "sde-dpmsolver": + assert noise is not None + if self.config.solver_type == "midpoint": + x_t = ( + (alpha_t / alpha_s0) * sample + - 2.0 * (sigma_t * (torch.exp(h) - 1.0)) * D0 + - (sigma_t * (torch.exp(h) - 1.0)) * D1 + + sigma_t * torch.sqrt(torch.exp(2 * h) - 1.0) * noise + ) + elif self.config.solver_type == "heun": + x_t = ( + (alpha_t / alpha_s0) * sample + - 2.0 * (sigma_t * (torch.exp(h) - 1.0)) * D0 + - 2.0 * (sigma_t * ((torch.exp(h) - 1.0) / h - 1.0)) * D1 + + sigma_t * torch.sqrt(torch.exp(2 * h) - 1.0) * noise + ) + return x_t + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.multistep_dpm_solver_third_order_update + def multistep_dpm_solver_third_order_update( + self, + model_output_list: List[torch.Tensor], + *args, + sample: torch.Tensor = None, + noise: Optional[torch.Tensor] = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the third-order multistep DPMSolver. + + Args: + model_output_list (`List[torch.Tensor]`): + The direct outputs from learned diffusion model at current and latter timesteps. + sample (`torch.Tensor`): + A current instance of a sample created by diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + + timestep_list = args[0] if len(args) > 0 else kwargs.pop("timestep_list", None) + prev_timestep = args[1] if len(args) > 1 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 2: + sample = args[2] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep_list is not None: + deprecate( + "timestep_list", + "1.0.0", + "Passing `timestep_list` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + sigma_t, sigma_s0, sigma_s1, sigma_s2 = ( + self.sigmas[self.step_index + 1], + self.sigmas[self.step_index], + self.sigmas[self.step_index - 1], + self.sigmas[self.step_index - 2], + ) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + alpha_s1, sigma_s1 = self._sigma_to_alpha_sigma_t(sigma_s1) + alpha_s2, sigma_s2 = self._sigma_to_alpha_sigma_t(sigma_s2) + + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s0 = torch.log(alpha_s0) - torch.log(sigma_s0) + lambda_s1 = torch.log(alpha_s1) - torch.log(sigma_s1) + lambda_s2 = torch.log(alpha_s2) - torch.log(sigma_s2) + + m0, m1, m2 = model_output_list[-1], model_output_list[-2], model_output_list[-3] + + h, h_0, h_1 = lambda_t - lambda_s0, lambda_s0 - lambda_s1, lambda_s1 - lambda_s2 + r0, r1 = h_0 / h, h_1 / h + D0 = m0 + D1_0, D1_1 = (1.0 / r0) * (m0 - m1), (1.0 / r1) * (m1 - m2) + D1 = D1_0 + (r0 / (r0 + r1)) * (D1_0 - D1_1) + D2 = (1.0 / (r0 + r1)) * (D1_0 - D1_1) + if self.config.algorithm_type == "dpmsolver++": + # See https://huggingface.co/papers/2206.00927 for detailed derivations + x_t = ( + (sigma_t / sigma_s0) * sample + - (alpha_t * (torch.exp(-h) - 1.0)) * D0 + + (alpha_t * ((torch.exp(-h) - 1.0) / h + 1.0)) * D1 + - (alpha_t * ((torch.exp(-h) - 1.0 + h) / h**2 - 0.5)) * D2 + ) + elif self.config.algorithm_type == "dpmsolver": + # See https://huggingface.co/papers/2206.00927 for detailed derivations + x_t = ( + (alpha_t / alpha_s0) * sample + - (sigma_t * (torch.exp(h) - 1.0)) * D0 + - (sigma_t * ((torch.exp(h) - 1.0) / h - 1.0)) * D1 + - (sigma_t * ((torch.exp(h) - 1.0 - h) / h**2 - 0.5)) * D2 + ) + elif self.config.algorithm_type == "sde-dpmsolver++": + assert noise is not None + x_t = ( + (sigma_t / sigma_s0 * torch.exp(-h)) * sample + + (alpha_t * (1.0 - torch.exp(-2.0 * h))) * D0 + + (alpha_t * ((1.0 - torch.exp(-2.0 * h)) / (-2.0 * h) + 1.0)) * D1 + + (alpha_t * ((1.0 - torch.exp(-2.0 * h) - 2.0 * h) / (2.0 * h) ** 2 - 0.5)) * D2 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + return x_t + + def _init_step_index(self, timestep): + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + + index_candidates = (self.timesteps == timestep).nonzero() + + if len(index_candidates) == 0: + step_index = len(self.timesteps) - 1 + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + elif len(index_candidates) > 1: + step_index = index_candidates[1].item() + else: + step_index = index_candidates[0].item() + + self._step_index = step_index + + def step( + self, + model_output: torch.Tensor, + timestep: Union[int, torch.Tensor], + sample: torch.Tensor, + generator=None, + variance_noise: Optional[torch.Tensor] = None, + return_dict: bool = True, + ) -> Union[SchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the sample with + the multistep DPMSolver. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + variance_noise (`torch.Tensor`): + Alternative to generating noise with `generator` by directly providing the noise for the variance + itself. Useful for methods such as [`CycleDiffusion`]. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_utils.SchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + if self.step_index is None: + self._init_step_index(timestep) + + # Improve numerical stability for small number of steps + lower_order_final = (self.step_index == len(self.timesteps) - 1) and ( + self.config.euler_at_final or (self.config.lower_order_final and len(self.timesteps) < 15) + ) + lower_order_second = ( + (self.step_index == len(self.timesteps) - 2) and self.config.lower_order_final and len(self.timesteps) < 15 + ) + + model_output = self.convert_model_output(model_output, sample=sample) + for i in range(self.config.solver_order - 1): + self.model_outputs[i] = self.model_outputs[i + 1] + self.model_outputs[-1] = model_output + + if self.config.algorithm_type in ["sde-dpmsolver", "sde-dpmsolver++"] and variance_noise is None: + noise = randn_tensor( + model_output.shape, generator=generator, device=model_output.device, dtype=model_output.dtype + ) + elif self.config.algorithm_type in ["sde-dpmsolver", "sde-dpmsolver++"]: + noise = variance_noise + else: + noise = None + + if self.config.solver_order == 1 or self.lower_order_nums < 1 or lower_order_final: + prev_sample = self.dpm_solver_first_order_update(model_output, sample=sample, noise=noise) + elif self.config.solver_order == 2 or self.lower_order_nums < 2 or lower_order_second: + prev_sample = self.multistep_dpm_solver_second_order_update(self.model_outputs, sample=sample, noise=noise) + else: + prev_sample = self.multistep_dpm_solver_third_order_update(self.model_outputs, sample=sample) + + if self.lower_order_nums < self.config.solver_order: + self.lower_order_nums += 1 + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return (prev_sample,) + + return SchedulerOutput(prev_sample=prev_sample) + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.scale_model_input + def scale_model_input(self, sample: torch.Tensor, *args, **kwargs) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + step_indices = [] + for timestep in timesteps: + index_candidates = (schedule_timesteps == timestep).nonzero() + if len(index_candidates) == 0: + step_index = len(schedule_timesteps) - 1 + elif len(index_candidates) > 1: + step_index = index_candidates[1].item() + else: + step_index = index_candidates[0].item() + step_indices.append(step_index) + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + noisy_samples = alpha_t * original_samples + sigma_t * noise + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_sde.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_sde.py new file mode 100644 index 0000000000000000000000000000000000000000..685ad6fd8c44e68a2748f1724a5e5c4e999ede29 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_sde.py @@ -0,0 +1,676 @@ +# Copyright 2024 Katherine Crowson, The HuggingFace Team and hlky. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch +import torchsde + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput, is_scipy_available +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin + + +if is_scipy_available(): + import scipy.stats + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->DPMSolverSDE +class DPMSolverSDESchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +class BatchedBrownianTree: + """A wrapper around torchsde.BrownianTree that enables batches of entropy.""" + + def __init__(self, x, t0, t1, seed=None, **kwargs): + t0, t1, self.sign = self.sort(t0, t1) + w0 = kwargs.get("w0", torch.zeros_like(x)) + if seed is None: + seed = torch.randint(0, 2**63 - 1, []).item() + self.batched = True + try: + assert len(seed) == x.shape[0] + w0 = w0[0] + except TypeError: + seed = [seed] + self.batched = False + self.trees = [ + torchsde.BrownianInterval( + t0=t0, + t1=t1, + size=w0.shape, + dtype=w0.dtype, + device=w0.device, + entropy=s, + tol=1e-6, + pool_size=24, + halfway_tree=True, + ) + for s in seed + ] + + @staticmethod + def sort(a, b): + return (a, b, 1) if a < b else (b, a, -1) + + def __call__(self, t0, t1): + t0, t1, sign = self.sort(t0, t1) + w = torch.stack([tree(t0, t1) for tree in self.trees]) * (self.sign * sign) + return w if self.batched else w[0] + + +class BrownianTreeNoiseSampler: + """A noise sampler backed by a torchsde.BrownianTree. + + Args: + x (Tensor): The tensor whose shape, device and dtype to use to generate + random samples. + sigma_min (float): The low end of the valid interval. + sigma_max (float): The high end of the valid interval. + seed (int or List[int]): The random seed. If a list of seeds is + supplied instead of a single integer, then the noise sampler will use one BrownianTree per batch item, each + with its own seed. + transform (callable): A function that maps sigma to the sampler's + internal timestep. + """ + + def __init__(self, x, sigma_min, sigma_max, seed=None, transform=lambda x: x): + self.transform = transform + t0, t1 = self.transform(torch.as_tensor(sigma_min)), self.transform(torch.as_tensor(sigma_max)) + self.tree = BatchedBrownianTree(x, t0, t1, seed) + + def __call__(self, sigma, sigma_next): + t0, t1 = self.transform(torch.as_tensor(sigma)), self.transform(torch.as_tensor(sigma_next)) + return self.tree(t0, t1) / (t1 - t0).abs().sqrt() + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +class DPMSolverSDEScheduler(SchedulerMixin, ConfigMixin): + """ + DPMSolverSDEScheduler implements the stochastic sampler from the [Elucidating the Design Space of Diffusion-Based + Generative Models](https://huggingface.co/papers/2206.00364) paper. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.00085): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.012): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear` or `scaled_linear`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + use_karras_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use Karras sigmas for step sizes in the noise schedule during the sampling process. If `True`, + the sigmas are determined according to a sequence of noise levels {σi}. + use_exponential_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use exponential sigmas for step sizes in the noise schedule during the sampling process. + use_beta_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use beta sigmas for step sizes in the noise schedule during the sampling process. Refer to [Beta + Sampling is All You Need](https://huggingface.co/papers/2407.12173) for more information. + noise_sampler_seed (`int`, *optional*, defaults to `None`): + The random seed to use for the noise sampler. If `None`, a random seed is generated. + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 2 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.00085, # sensible defaults + beta_end: float = 0.012, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + prediction_type: str = "epsilon", + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + noise_sampler_seed: Optional[int] = None, + timestep_spacing: str = "linspace", + steps_offset: int = 0, + ): + if self.config.use_beta_sigmas and not is_scipy_available(): + raise ImportError("Make sure to install scipy if you want to use beta sigmas.") + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + # set all values + self.set_timesteps(num_train_timesteps, None, num_train_timesteps) + self.use_karras_sigmas = use_karras_sigmas + self.noise_sampler = None + self.noise_sampler_seed = noise_sampler_seed + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._init_step_index + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + @property + def init_noise_sigma(self): + # standard deviation of the initial noise distribution + if self.config.timestep_spacing in ["linspace", "trailing"]: + return self.sigmas.max() + + return (self.sigmas.max() ** 2 + 1) ** 0.5 + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def scale_model_input( + self, + sample: torch.Tensor, + timestep: Union[float, torch.Tensor], + ) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + if self.step_index is None: + self._init_step_index(timestep) + + sigma = self.sigmas[self.step_index] + sigma_input = sigma if self.state_in_first_order else self.mid_point_sigma + sample = sample / ((sigma_input**2 + 1) ** 0.5) + return sample + + def set_timesteps( + self, + num_inference_steps: int, + device: Union[str, torch.device] = None, + num_train_timesteps: Optional[int] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + self.num_inference_steps = num_inference_steps + + num_train_timesteps = num_train_timesteps or self.config.num_train_timesteps + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = np.linspace(0, num_train_timesteps - 1, num_inference_steps, dtype=float)[::-1].copy() + elif self.config.timestep_spacing == "leading": + step_ratio = num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(float) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(num_train_timesteps, 0, -step_ratio)).round().copy().astype(float) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + log_sigmas = np.log(sigmas) + sigmas = np.interp(timesteps, np.arange(0, len(sigmas)), sigmas) + + if self.config.use_karras_sigmas: + sigmas = self._convert_to_karras(in_sigmas=sigmas) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + elif self.config.use_exponential_sigmas: + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + elif self.config.use_beta_sigmas: + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + + second_order_timesteps = self._second_order_timesteps(sigmas, log_sigmas) + + sigmas = np.concatenate([sigmas, [0.0]]).astype(np.float32) + sigmas = torch.from_numpy(sigmas).to(device=device) + self.sigmas = torch.cat([sigmas[:1], sigmas[1:-1].repeat_interleave(2), sigmas[-1:]]) + + timesteps = torch.from_numpy(timesteps) + second_order_timesteps = torch.from_numpy(second_order_timesteps) + timesteps = torch.cat([timesteps[:1], timesteps[1:].repeat_interleave(2)]) + timesteps[1::2] = second_order_timesteps + + if str(device).startswith("mps"): + # mps does not support float64 + self.timesteps = timesteps.to(device, dtype=torch.float32) + else: + self.timesteps = timesteps.to(device=device) + + # empty first order variables + self.sample = None + self.mid_point_sigma = None + + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + self.noise_sampler = None + + def _second_order_timesteps(self, sigmas, log_sigmas): + def sigma_fn(_t): + return np.exp(-_t) + + def t_fn(_sigma): + return -np.log(_sigma) + + midpoint_ratio = 0.5 + t = t_fn(sigmas) + delta_time = np.diff(t) + t_proposed = t[:-1] + delta_time * midpoint_ratio + sig_proposed = sigma_fn(t_proposed) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sig_proposed]) + return timesteps + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._sigma_to_t + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + # copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_karras + def _convert_to_karras(self, in_sigmas: torch.Tensor) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + sigma_min: float = in_sigmas[-1].item() + sigma_max: float = in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, self.num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_exponential + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_beta + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + @property + def state_in_first_order(self): + return self.sample is None + + def step( + self, + model_output: Union[torch.Tensor, np.ndarray], + timestep: Union[float, torch.Tensor], + sample: Union[torch.Tensor, np.ndarray], + return_dict: bool = True, + s_noise: float = 1.0, + ) -> Union[DPMSolverSDESchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor` or `np.ndarray`): + The direct output from learned diffusion model. + timestep (`float` or `torch.Tensor`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor` or `np.ndarray`): + A current instance of a sample created by the diffusion process. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_dpmsolver_sde.DPMSolverSDESchedulerOutput`] or + tuple. + s_noise (`float`, *optional*, defaults to 1.0): + Scaling factor for noise added to the sample. + + Returns: + [`~schedulers.scheduling_dpmsolver_sde.DPMSolverSDESchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_dpmsolver_sde.DPMSolverSDESchedulerOutput`] is + returned, otherwise a tuple is returned where the first element is the sample tensor. + """ + if self.step_index is None: + self._init_step_index(timestep) + + # Create a noise sampler if it hasn't been created yet + if self.noise_sampler is None: + min_sigma, max_sigma = self.sigmas[self.sigmas > 0].min(), self.sigmas.max() + self.noise_sampler = BrownianTreeNoiseSampler(sample, min_sigma, max_sigma, self.noise_sampler_seed) + + # Define functions to compute sigma and t from each other + def sigma_fn(_t: torch.Tensor) -> torch.Tensor: + return _t.neg().exp() + + def t_fn(_sigma: torch.Tensor) -> torch.Tensor: + return _sigma.log().neg() + + if self.state_in_first_order: + sigma = self.sigmas[self.step_index] + sigma_next = self.sigmas[self.step_index + 1] + else: + # 2nd order + sigma = self.sigmas[self.step_index - 1] + sigma_next = self.sigmas[self.step_index] + + # Set the midpoint and step size for the current step + midpoint_ratio = 0.5 + t, t_next = t_fn(sigma), t_fn(sigma_next) + delta_time = t_next - t + t_proposed = t + delta_time * midpoint_ratio + + # 1. compute predicted original sample (x_0) from sigma-scaled predicted noise + if self.config.prediction_type == "epsilon": + sigma_input = sigma if self.state_in_first_order else sigma_fn(t_proposed) + pred_original_sample = sample - sigma_input * model_output + elif self.config.prediction_type == "v_prediction": + sigma_input = sigma if self.state_in_first_order else sigma_fn(t_proposed) + pred_original_sample = model_output * (-sigma_input / (sigma_input**2 + 1) ** 0.5) + ( + sample / (sigma_input**2 + 1) + ) + elif self.config.prediction_type == "sample": + raise NotImplementedError("prediction_type not implemented yet: sample") + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, or `v_prediction`" + ) + + if sigma_next == 0: + derivative = (sample - pred_original_sample) / sigma + dt = sigma_next - sigma + prev_sample = sample + derivative * dt + else: + if self.state_in_first_order: + t_next = t_proposed + else: + sample = self.sample + + sigma_from = sigma_fn(t) + sigma_to = sigma_fn(t_next) + sigma_up = min(sigma_to, (sigma_to**2 * (sigma_from**2 - sigma_to**2) / sigma_from**2) ** 0.5) + sigma_down = (sigma_to**2 - sigma_up**2) ** 0.5 + ancestral_t = t_fn(sigma_down) + prev_sample = (sigma_fn(ancestral_t) / sigma_fn(t)) * sample - ( + t - ancestral_t + ).expm1() * pred_original_sample + prev_sample = prev_sample + self.noise_sampler(sigma_fn(t), sigma_fn(t_next)) * s_noise * sigma_up + + if self.state_in_first_order: + # store for 2nd order step + self.sample = sample + self.mid_point_sigma = sigma_fn(t_next) + else: + # free for "first order mode" + self.sample = None + self.mid_point_sigma = None + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return ( + prev_sample, + pred_original_sample, + ) + + return DPMSolverSDESchedulerOutput(prev_sample=prev_sample, pred_original_sample=pred_original_sample) + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.Tensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # self.begin_index is None when scheduler is used for training, or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + noisy_samples = original_samples + noise * sigma + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_singlestep.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_singlestep.py new file mode 100644 index 0000000000000000000000000000000000000000..39efca78423c3acc0d6b04bc9b22ce346781dfe7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_dpmsolver_singlestep.py @@ -0,0 +1,1168 @@ +# Copyright 2024 TSAIL Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/LuChengTHU/dpm-solver + +import math +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import deprecate, is_scipy_available, logging +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin, SchedulerOutput + + +if is_scipy_available(): + import scipy.stats + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +class DPMSolverSinglestepScheduler(SchedulerMixin, ConfigMixin): + """ + `DPMSolverSinglestepScheduler` is a fast dedicated high-order solver for diffusion ODEs. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + solver_order (`int`, defaults to 2): + The DPMSolver order which can be `1` or `2` or `3`. It is recommended to use `solver_order=2` for guided + sampling, and `solver_order=3` for unconditional sampling. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + thresholding (`bool`, defaults to `False`): + Whether to use the "dynamic thresholding" method. This is unsuitable for latent-space diffusion models such + as Stable Diffusion. + dynamic_thresholding_ratio (`float`, defaults to 0.995): + The ratio for the dynamic thresholding method. Valid only when `thresholding=True`. + sample_max_value (`float`, defaults to 1.0): + The threshold value for dynamic thresholding. Valid only when `thresholding=True` and + `algorithm_type="dpmsolver++"`. + algorithm_type (`str`, defaults to `dpmsolver++`): + Algorithm type for the solver; can be `dpmsolver` or `dpmsolver++` or `sde-dpmsolver++`. The `dpmsolver` + type implements the algorithms in the [DPMSolver](https://huggingface.co/papers/2206.00927) paper, and the + `dpmsolver++` type implements the algorithms in the [DPMSolver++](https://huggingface.co/papers/2211.01095) + paper. It is recommended to use `dpmsolver++` or `sde-dpmsolver++` with `solver_order=2` for guided + sampling like in Stable Diffusion. + solver_type (`str`, defaults to `midpoint`): + Solver type for the second-order solver; can be `midpoint` or `heun`. The solver type slightly affects the + sample quality, especially for a small number of steps. It is recommended to use `midpoint` solvers. + lower_order_final (`bool`, defaults to `True`): + Whether to use lower-order solvers in the final steps. Only valid for < 15 inference steps. This can + stabilize the sampling of DPMSolver for steps < 15, especially for steps <= 10. + use_karras_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use Karras sigmas for step sizes in the noise schedule during the sampling process. If `True`, + the sigmas are determined according to a sequence of noise levels {σi}. + use_exponential_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use exponential sigmas for step sizes in the noise schedule during the sampling process. + use_beta_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use beta sigmas for step sizes in the noise schedule during the sampling process. Refer to [Beta + Sampling is All You Need](https://huggingface.co/papers/2407.12173) for more information. + final_sigmas_type (`str`, *optional*, defaults to `"zero"`): + The final `sigma` value for the noise schedule during the sampling process. If `"sigma_min"`, the final + sigma is the same as the last sigma in the training schedule. If `zero`, the final sigma is set to 0. + lambda_min_clipped (`float`, defaults to `-inf`): + Clipping threshold for the minimum value of `lambda(t)` for numerical stability. This is critical for the + cosine (`squaredcos_cap_v2`) noise schedule. + variance_type (`str`, *optional*): + Set to "learned" or "learned_range" for diffusion models that predict variance. If set, the model's output + contains the predicted Gaussian variance. + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[np.ndarray] = None, + solver_order: int = 2, + prediction_type: str = "epsilon", + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + sample_max_value: float = 1.0, + algorithm_type: str = "dpmsolver++", + solver_type: str = "midpoint", + lower_order_final: bool = False, + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + use_flow_sigmas: Optional[bool] = False, + flow_shift: Optional[float] = 1.0, + final_sigmas_type: Optional[str] = "zero", # "zero", "sigma_min" + lambda_min_clipped: float = -float("inf"), + variance_type: Optional[str] = None, + ): + if self.config.use_beta_sigmas and not is_scipy_available(): + raise ImportError("Make sure to install scipy if you want to use beta sigmas.") + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if algorithm_type == "dpmsolver": + deprecation_message = "algorithm_type `dpmsolver` is deprecated and will be removed in a future version. Choose from `dpmsolver++` or `sde-dpmsolver++` instead" + deprecate("algorithm_types=dpmsolver", "1.0.0", deprecation_message) + + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + # Currently we only support VP-type noise schedule + self.alpha_t = torch.sqrt(self.alphas_cumprod) + self.sigma_t = torch.sqrt(1 - self.alphas_cumprod) + self.lambda_t = torch.log(self.alpha_t) - torch.log(self.sigma_t) + self.sigmas = ((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5 + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # settings for DPM-Solver + if algorithm_type not in ["dpmsolver", "dpmsolver++", "sde-dpmsolver++"]: + if algorithm_type == "deis": + self.register_to_config(algorithm_type="dpmsolver++") + else: + raise NotImplementedError(f"{algorithm_type} is not implemented for {self.__class__}") + if solver_type not in ["midpoint", "heun"]: + if solver_type in ["logrho", "bh1", "bh2"]: + self.register_to_config(solver_type="midpoint") + else: + raise NotImplementedError(f"{solver_type} is not implemented for {self.__class__}") + + if algorithm_type not in ["dpmsolver++", "sde-dpmsolver++"] and final_sigmas_type == "zero": + raise ValueError( + f"`final_sigmas_type` {final_sigmas_type} is not supported for `algorithm_type` {algorithm_type}. Please choose `sigma_min` instead." + ) + + # setable values + self.num_inference_steps = None + timesteps = np.linspace(0, num_train_timesteps - 1, num_train_timesteps, dtype=np.float32)[::-1].copy() + self.timesteps = torch.from_numpy(timesteps) + self.model_outputs = [None] * solver_order + self.sample = None + self.order_list = self.get_order_list(num_train_timesteps) + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + def get_order_list(self, num_inference_steps: int) -> List[int]: + """ + Computes the solver order at each time step. + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + """ + steps = num_inference_steps + order = self.config.solver_order + if order > 3: + raise ValueError("Order > 3 is not supported by this scheduler") + if self.config.lower_order_final: + if order == 3: + if steps % 3 == 0: + orders = [1, 2, 3] * (steps // 3 - 1) + [1, 2] + [1] + elif steps % 3 == 1: + orders = [1, 2, 3] * (steps // 3) + [1] + else: + orders = [1, 2, 3] * (steps // 3) + [1, 2] + elif order == 2: + if steps % 2 == 0: + orders = [1, 2] * (steps // 2 - 1) + [1, 1] + else: + orders = [1, 2] * (steps // 2) + [1] + elif order == 1: + orders = [1] * steps + else: + if order == 3: + orders = [1, 2, 3] * (steps // 3) + elif order == 2: + orders = [1, 2] * (steps // 2) + elif order == 1: + orders = [1] * steps + + if self.config.final_sigmas_type == "zero": + orders[-1] = 1 + + return orders + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def set_timesteps( + self, + num_inference_steps: int = None, + device: Union[str, torch.device] = None, + timesteps: Optional[List[int]] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + timesteps (`List[int]`, *optional*): + Custom timesteps used to support arbitrary spacing between timesteps. If `None`, then the default + timestep spacing strategy of equal spacing between timesteps schedule is used. If `timesteps` is + passed, `num_inference_steps` must be `None`. + """ + if num_inference_steps is None and timesteps is None: + raise ValueError("Must pass exactly one of `num_inference_steps` or `timesteps`.") + if num_inference_steps is not None and timesteps is not None: + raise ValueError("Must pass exactly one of `num_inference_steps` or `timesteps`.") + if timesteps is not None and self.config.use_karras_sigmas: + raise ValueError("Cannot use `timesteps` when `config.use_karras_sigmas=True`.") + if timesteps is not None and self.config.use_exponential_sigmas: + raise ValueError("Cannot set `timesteps` with `config.use_exponential_sigmas = True`.") + if timesteps is not None and self.config.use_beta_sigmas: + raise ValueError("Cannot set `timesteps` with `config.use_beta_sigmas = True`.") + + num_inference_steps = num_inference_steps or len(timesteps) + self.num_inference_steps = num_inference_steps + + if timesteps is not None: + timesteps = np.array(timesteps).astype(np.int64) + else: + # Clipping the minimum of all lambda(t) for numerical stability. + # This is critical for cosine (squaredcos_cap_v2) noise schedule. + clipped_idx = torch.searchsorted(torch.flip(self.lambda_t, [0]), self.config.lambda_min_clipped) + clipped_idx = clipped_idx.item() + timesteps = ( + np.linspace(0, self.config.num_train_timesteps - 1 - clipped_idx, num_inference_steps + 1) + .round()[::-1][:-1] + .copy() + .astype(np.int64) + ) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + log_sigmas = np.log(sigmas) + if self.config.use_karras_sigmas: + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_karras(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]).round() + elif self.config.use_exponential_sigmas: + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + elif self.config.use_beta_sigmas: + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + elif self.config.use_flow_sigmas: + alphas = np.linspace(1, 1 / self.config.num_train_timesteps, num_inference_steps + 1) + sigmas = 1.0 - alphas + sigmas = np.flip(self.config.flow_shift * sigmas / (1 + (self.config.flow_shift - 1) * sigmas))[:-1].copy() + timesteps = (sigmas * self.config.num_train_timesteps).copy() + else: + sigmas = np.interp(timesteps, np.arange(0, len(sigmas)), sigmas) + + if self.config.final_sigmas_type == "sigma_min": + sigma_last = ((1 - self.alphas_cumprod[0]) / self.alphas_cumprod[0]) ** 0.5 + elif self.config.final_sigmas_type == "zero": + sigma_last = 0 + else: + raise ValueError( + f" `final_sigmas_type` must be one of `sigma_min` or `zero`, but got {self.config.final_sigmas_type}" + ) + sigmas = np.concatenate([sigmas, [sigma_last]]).astype(np.float32) + + self.sigmas = torch.from_numpy(sigmas).to(device=device) + + self.timesteps = torch.from_numpy(timesteps).to(device=device, dtype=torch.int64) + self.model_outputs = [None] * self.config.solver_order + self.sample = None + + if not self.config.lower_order_final and num_inference_steps % self.config.solver_order != 0: + logger.warning( + "Changing scheduler {self.config} to have `lower_order_final` set to True to handle uneven amount of inference steps. Please make sure to always use an even number of `num_inference steps when using `lower_order_final=False`." + ) + self.register_to_config(lower_order_final=True) + + if not self.config.lower_order_final and self.config.final_sigmas_type == "zero": + logger.warning( + " `last_sigmas_type='zero'` is not supported for `lower_order_final=False`. Changing scheduler {self.config} to have `lower_order_final` set to True." + ) + self.register_to_config(lower_order_final=True) + + self.order_list = self.get_order_list(num_inference_steps) + + # add an index counter for schedulers that allow duplicated timesteps + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler._threshold_sample + def _threshold_sample(self, sample: torch.Tensor) -> torch.Tensor: + """ + "Dynamic thresholding: At each sampling step we set s to a certain percentile absolute pixel value in xt0 (the + prediction of x_0 at timestep t), and if s > 1, then we threshold xt0 to the range [-s, s] and then divide by + s. Dynamic thresholding pushes saturated pixels (those near -1 and 1) inwards, thereby actively preventing + pixels from saturation at each step. We find that dynamic thresholding results in significantly better + photorealism as well as better image-text alignment, especially when using very large guidance weights." + + https://huggingface.co/papers/2205.11487 + """ + dtype = sample.dtype + batch_size, channels, *remaining_dims = sample.shape + + if dtype not in (torch.float32, torch.float64): + sample = sample.float() # upcast for quantile calculation, and clamp not implemented for cpu half + + # Flatten sample for doing quantile calculation along each image + sample = sample.reshape(batch_size, channels * np.prod(remaining_dims)) + + abs_sample = sample.abs() # "a certain percentile absolute pixel value" + + s = torch.quantile(abs_sample, self.config.dynamic_thresholding_ratio, dim=1) + s = torch.clamp( + s, min=1, max=self.config.sample_max_value + ) # When clamped to min=1, equivalent to standard clipping to [-1, 1] + s = s.unsqueeze(1) # (batch_size, 1) because clamp will broadcast along dim=0 + sample = torch.clamp(sample, -s, s) / s # "we threshold xt0 to the range [-s, s] and then divide by s" + + sample = sample.reshape(batch_size, channels, *remaining_dims) + sample = sample.to(dtype) + + return sample + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._sigma_to_t + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler._sigma_to_alpha_sigma_t + def _sigma_to_alpha_sigma_t(self, sigma): + if self.config.use_flow_sigmas: + alpha_t = 1 - sigma + sigma_t = sigma + else: + alpha_t = 1 / ((sigma**2 + 1) ** 0.5) + sigma_t = sigma * alpha_t + + return alpha_t, sigma_t + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_karras + def _convert_to_karras(self, in_sigmas: torch.Tensor, num_inference_steps) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_exponential + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_beta + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + def convert_model_output( + self, + model_output: torch.Tensor, + *args, + sample: torch.Tensor = None, + **kwargs, + ) -> torch.Tensor: + """ + Convert the model output to the corresponding type the DPMSolver/DPMSolver++ algorithm needs. DPM-Solver is + designed to discretize an integral of the noise prediction model, and DPM-Solver++ is designed to discretize an + integral of the data prediction model. + + + + The algorithm and model type are decoupled. You can use either DPMSolver or DPMSolver++ for both noise + prediction and data prediction models. + + + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The converted model output. + """ + timestep = args[0] if len(args) > 0 else kwargs.pop("timestep", None) + if sample is None: + if len(args) > 1: + sample = args[1] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep is not None: + deprecate( + "timesteps", + "1.0.0", + "Passing `timesteps` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + # DPM-Solver++ needs to solve an integral of the data prediction model. + if self.config.algorithm_type in ["dpmsolver++", "sde-dpmsolver++"]: + if self.config.prediction_type == "epsilon": + # DPM-Solver and DPM-Solver++ only need the "mean" output. + if self.config.variance_type in ["learned", "learned_range"]: + model_output = model_output[:, :3] + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + x0_pred = (sample - sigma_t * model_output) / alpha_t + elif self.config.prediction_type == "sample": + x0_pred = model_output + elif self.config.prediction_type == "v_prediction": + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + x0_pred = alpha_t * sample - sigma_t * model_output + elif self.config.prediction_type == "flow_prediction": + sigma_t = self.sigmas[self.step_index] + x0_pred = sample - sigma_t * model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, " + "`v_prediction`, or `flow_prediction` for the DPMSolverSinglestepScheduler." + ) + + if self.config.thresholding: + x0_pred = self._threshold_sample(x0_pred) + + return x0_pred + + # DPM-Solver needs to solve an integral of the noise prediction model. + elif self.config.algorithm_type == "dpmsolver": + if self.config.prediction_type == "epsilon": + # DPM-Solver and DPM-Solver++ only need the "mean" output. + if self.config.variance_type in ["learned", "learned_range"]: + epsilon = model_output[:, :3] + else: + epsilon = model_output + elif self.config.prediction_type == "sample": + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + epsilon = (sample - alpha_t * model_output) / sigma_t + elif self.config.prediction_type == "v_prediction": + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + epsilon = alpha_t * model_output + sigma_t * sample + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, or" + " `v_prediction` for the DPMSolverSinglestepScheduler." + ) + + if self.config.thresholding: + alpha_t, sigma_t = self.alpha_t[timestep], self.sigma_t[timestep] + x0_pred = (sample - sigma_t * epsilon) / alpha_t + x0_pred = self._threshold_sample(x0_pred) + epsilon = (sample - alpha_t * x0_pred) / sigma_t + + return epsilon + + def dpm_solver_first_order_update( + self, + model_output: torch.Tensor, + *args, + sample: torch.Tensor = None, + noise: Optional[torch.Tensor] = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the first-order DPMSolver (equivalent to DDIM). + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + prev_timestep (`int`): + The previous discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + timestep = args[0] if len(args) > 0 else kwargs.pop("timestep", None) + prev_timestep = args[1] if len(args) > 1 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 2: + sample = args[2] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep is not None: + deprecate( + "timesteps", + "1.0.0", + "Passing `timesteps` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + sigma_t, sigma_s = self.sigmas[self.step_index + 1], self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s, sigma_s = self._sigma_to_alpha_sigma_t(sigma_s) + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s = torch.log(alpha_s) - torch.log(sigma_s) + h = lambda_t - lambda_s + if self.config.algorithm_type == "dpmsolver++": + x_t = (sigma_t / sigma_s) * sample - (alpha_t * (torch.exp(-h) - 1.0)) * model_output + elif self.config.algorithm_type == "dpmsolver": + x_t = (alpha_t / alpha_s) * sample - (sigma_t * (torch.exp(h) - 1.0)) * model_output + elif self.config.algorithm_type == "sde-dpmsolver++": + assert noise is not None + x_t = ( + (sigma_t / sigma_s * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * model_output + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + return x_t + + def singlestep_dpm_solver_second_order_update( + self, + model_output_list: List[torch.Tensor], + *args, + sample: torch.Tensor = None, + noise: Optional[torch.Tensor] = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the second-order singlestep DPMSolver that computes the solution at time `prev_timestep` from the + time `timestep_list[-2]`. + + Args: + model_output_list (`List[torch.Tensor]`): + The direct outputs from learned diffusion model at current and latter timesteps. + timestep (`int`): + The current and latter discrete timestep in the diffusion chain. + prev_timestep (`int`): + The previous discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + timestep_list = args[0] if len(args) > 0 else kwargs.pop("timestep_list", None) + prev_timestep = args[1] if len(args) > 1 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 2: + sample = args[2] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep_list is not None: + deprecate( + "timestep_list", + "1.0.0", + "Passing `timestep_list` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + sigma_t, sigma_s0, sigma_s1 = ( + self.sigmas[self.step_index + 1], + self.sigmas[self.step_index], + self.sigmas[self.step_index - 1], + ) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + alpha_s1, sigma_s1 = self._sigma_to_alpha_sigma_t(sigma_s1) + + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s0 = torch.log(alpha_s0) - torch.log(sigma_s0) + lambda_s1 = torch.log(alpha_s1) - torch.log(sigma_s1) + + m0, m1 = model_output_list[-1], model_output_list[-2] + + h, h_0 = lambda_t - lambda_s1, lambda_s0 - lambda_s1 + r0 = h_0 / h + D0, D1 = m1, (1.0 / r0) * (m0 - m1) + if self.config.algorithm_type == "dpmsolver++": + # See https://huggingface.co/papers/2211.01095 for detailed derivations + if self.config.solver_type == "midpoint": + x_t = ( + (sigma_t / sigma_s1) * sample + - (alpha_t * (torch.exp(-h) - 1.0)) * D0 + - 0.5 * (alpha_t * (torch.exp(-h) - 1.0)) * D1 + ) + elif self.config.solver_type == "heun": + x_t = ( + (sigma_t / sigma_s1) * sample + - (alpha_t * (torch.exp(-h) - 1.0)) * D0 + + (alpha_t * ((torch.exp(-h) - 1.0) / h + 1.0)) * D1 + ) + elif self.config.algorithm_type == "dpmsolver": + # See https://huggingface.co/papers/2206.00927 for detailed derivations + if self.config.solver_type == "midpoint": + x_t = ( + (alpha_t / alpha_s1) * sample + - (sigma_t * (torch.exp(h) - 1.0)) * D0 + - 0.5 * (sigma_t * (torch.exp(h) - 1.0)) * D1 + ) + elif self.config.solver_type == "heun": + x_t = ( + (alpha_t / alpha_s1) * sample + - (sigma_t * (torch.exp(h) - 1.0)) * D0 + - (sigma_t * ((torch.exp(h) - 1.0) / h - 1.0)) * D1 + ) + elif self.config.algorithm_type == "sde-dpmsolver++": + assert noise is not None + if self.config.solver_type == "midpoint": + x_t = ( + (sigma_t / sigma_s1 * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * D0 + + 0.5 * (alpha_t * (1 - torch.exp(-2.0 * h))) * D1 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + elif self.config.solver_type == "heun": + x_t = ( + (sigma_t / sigma_s1 * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * D0 + + (alpha_t * ((1.0 - torch.exp(-2.0 * h)) / (-2.0 * h) + 1.0)) * D1 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + return x_t + + def singlestep_dpm_solver_third_order_update( + self, + model_output_list: List[torch.Tensor], + *args, + sample: torch.Tensor = None, + noise: Optional[torch.Tensor] = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the third-order singlestep DPMSolver that computes the solution at time `prev_timestep` from the + time `timestep_list[-3]`. + + Args: + model_output_list (`List[torch.Tensor]`): + The direct outputs from learned diffusion model at current and latter timesteps. + timestep (`int`): + The current and latter discrete timestep in the diffusion chain. + prev_timestep (`int`): + The previous discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + + timestep_list = args[0] if len(args) > 0 else kwargs.pop("timestep_list", None) + prev_timestep = args[1] if len(args) > 1 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 2: + sample = args[2] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep_list is not None: + deprecate( + "timestep_list", + "1.0.0", + "Passing `timestep_list` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + sigma_t, sigma_s0, sigma_s1, sigma_s2 = ( + self.sigmas[self.step_index + 1], + self.sigmas[self.step_index], + self.sigmas[self.step_index - 1], + self.sigmas[self.step_index - 2], + ) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + alpha_s1, sigma_s1 = self._sigma_to_alpha_sigma_t(sigma_s1) + alpha_s2, sigma_s2 = self._sigma_to_alpha_sigma_t(sigma_s2) + + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s0 = torch.log(alpha_s0) - torch.log(sigma_s0) + lambda_s1 = torch.log(alpha_s1) - torch.log(sigma_s1) + lambda_s2 = torch.log(alpha_s2) - torch.log(sigma_s2) + + m0, m1, m2 = model_output_list[-1], model_output_list[-2], model_output_list[-3] + + h, h_0, h_1 = lambda_t - lambda_s2, lambda_s0 - lambda_s2, lambda_s1 - lambda_s2 + r0, r1 = h_0 / h, h_1 / h + D0 = m2 + D1_0, D1_1 = (1.0 / r1) * (m1 - m2), (1.0 / r0) * (m0 - m2) + D1 = (r0 * D1_0 - r1 * D1_1) / (r0 - r1) + D2 = 2.0 * (D1_1 - D1_0) / (r0 - r1) + if self.config.algorithm_type == "dpmsolver++": + # See https://huggingface.co/papers/2206.00927 for detailed derivations + if self.config.solver_type == "midpoint": + x_t = ( + (sigma_t / sigma_s2) * sample + - (alpha_t * (torch.exp(-h) - 1.0)) * D0 + + (alpha_t * ((torch.exp(-h) - 1.0) / h + 1.0)) * D1_1 + ) + elif self.config.solver_type == "heun": + x_t = ( + (sigma_t / sigma_s2) * sample + - (alpha_t * (torch.exp(-h) - 1.0)) * D0 + + (alpha_t * ((torch.exp(-h) - 1.0) / h + 1.0)) * D1 + - (alpha_t * ((torch.exp(-h) - 1.0 + h) / h**2 - 0.5)) * D2 + ) + elif self.config.algorithm_type == "dpmsolver": + # See https://huggingface.co/papers/2206.00927 for detailed derivations + if self.config.solver_type == "midpoint": + x_t = ( + (alpha_t / alpha_s2) * sample + - (sigma_t * (torch.exp(h) - 1.0)) * D0 + - (sigma_t * ((torch.exp(h) - 1.0) / h - 1.0)) * D1_1 + ) + elif self.config.solver_type == "heun": + x_t = ( + (alpha_t / alpha_s2) * sample + - (sigma_t * (torch.exp(h) - 1.0)) * D0 + - (sigma_t * ((torch.exp(h) - 1.0) / h - 1.0)) * D1 + - (sigma_t * ((torch.exp(h) - 1.0 - h) / h**2 - 0.5)) * D2 + ) + elif self.config.algorithm_type == "sde-dpmsolver++": + assert noise is not None + if self.config.solver_type == "midpoint": + x_t = ( + (sigma_t / sigma_s2 * torch.exp(-h)) * sample + + (alpha_t * (1.0 - torch.exp(-2.0 * h))) * D0 + + (alpha_t * ((1.0 - torch.exp(-2.0 * h)) / (-2.0 * h) + 1.0)) * D1_1 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + elif self.config.solver_type == "heun": + x_t = ( + (sigma_t / sigma_s2 * torch.exp(-h)) * sample + + (alpha_t * (1.0 - torch.exp(-2.0 * h))) * D0 + + (alpha_t * ((1.0 - torch.exp(-2.0 * h)) / (-2.0 * h) + 1.0)) * D1 + + (alpha_t * ((1.0 - torch.exp(-2.0 * h) + (-2.0 * h)) / (-2.0 * h) ** 2 - 0.5)) * D2 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + return x_t + + def singlestep_dpm_solver_update( + self, + model_output_list: List[torch.Tensor], + *args, + sample: torch.Tensor = None, + order: int = None, + noise: Optional[torch.Tensor] = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the singlestep DPMSolver. + + Args: + model_output_list (`List[torch.Tensor]`): + The direct outputs from learned diffusion model at current and latter timesteps. + timestep (`int`): + The current and latter discrete timestep in the diffusion chain. + prev_timestep (`int`): + The previous discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by diffusion process. + order (`int`): + The solver order at this step. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + timestep_list = args[0] if len(args) > 0 else kwargs.pop("timestep_list", None) + prev_timestep = args[1] if len(args) > 1 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 2: + sample = args[2] + else: + raise ValueError("missing `sample` as a required keyword argument") + if order is None: + if len(args) > 3: + order = args[3] + else: + raise ValueError("missing `order` as a required keyword argument") + if timestep_list is not None: + deprecate( + "timestep_list", + "1.0.0", + "Passing `timestep_list` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + if order == 1: + return self.dpm_solver_first_order_update(model_output_list[-1], sample=sample, noise=noise) + elif order == 2: + return self.singlestep_dpm_solver_second_order_update(model_output_list, sample=sample, noise=noise) + elif order == 3: + return self.singlestep_dpm_solver_third_order_update(model_output_list, sample=sample, noise=noise) + else: + raise ValueError(f"Order must be 1, 2, 3, got {order}") + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + index_candidates = (schedule_timesteps == timestep).nonzero() + + if len(index_candidates) == 0: + step_index = len(self.timesteps) - 1 + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + elif len(index_candidates) > 1: + step_index = index_candidates[1].item() + else: + step_index = index_candidates[0].item() + + return step_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler._init_step_index + def _init_step_index(self, timestep): + """ + Initialize the step_index counter for the scheduler. + """ + + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.Tensor, + timestep: Union[int, torch.Tensor], + sample: torch.Tensor, + generator=None, + return_dict: bool = True, + ) -> Union[SchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the sample with + the singlestep DPMSolver. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_utils.SchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + if self.step_index is None: + self._init_step_index(timestep) + + model_output = self.convert_model_output(model_output, sample=sample) + for i in range(self.config.solver_order - 1): + self.model_outputs[i] = self.model_outputs[i + 1] + self.model_outputs[-1] = model_output + + if self.config.algorithm_type == "sde-dpmsolver++": + noise = randn_tensor( + model_output.shape, generator=generator, device=model_output.device, dtype=model_output.dtype + ) + else: + noise = None + + order = self.order_list[self.step_index] + + # For img2img denoising might start with order>1 which is not possible + # In this case make sure that the first two steps are both order=1 + while self.model_outputs[-order] is None: + order -= 1 + + # For single-step solvers, we use the initial value at each time with order = 1. + if order == 1: + self.sample = sample + + prev_sample = self.singlestep_dpm_solver_update( + self.model_outputs, sample=self.sample, order=order, noise=noise + ) + + # upon completion increase step index by one, noise=noise + self._step_index += 1 + + if not return_dict: + return (prev_sample,) + + return SchedulerOutput(prev_sample=prev_sample) + + def scale_model_input(self, sample: torch.Tensor, *args, **kwargs) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # begin_index is None when the scheduler is used for training or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + noisy_samples = alpha_t * original_samples + sigma_t * noise + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_edm_dpmsolver_multistep.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_edm_dpmsolver_multistep.py new file mode 100644 index 0000000000000000000000000000000000000000..3e85bde5bea00c0350707f4d189aaabe765e597e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_edm_dpmsolver_multistep.py @@ -0,0 +1,712 @@ +# Copyright 2024 TSAIL Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/LuChengTHU/dpm-solver and https://github.com/NVlabs/edm + +import math +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import SchedulerMixin, SchedulerOutput + + +class EDMDPMSolverMultistepScheduler(SchedulerMixin, ConfigMixin): + """ + Implements DPMSolverMultistepScheduler in EDM formulation as presented in Karras et al. 2022 [1]. + `EDMDPMSolverMultistepScheduler` is a fast dedicated high-order solver for diffusion ODEs. + + [1] Karras, Tero, et al. "Elucidating the Design Space of Diffusion-Based Generative Models." + https://huggingface.co/papers/2206.00364 + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + sigma_min (`float`, *optional*, defaults to 0.002): + Minimum noise magnitude in the sigma schedule. This was set to 0.002 in the EDM paper [1]; a reasonable + range is [0, 10]. + sigma_max (`float`, *optional*, defaults to 80.0): + Maximum noise magnitude in the sigma schedule. This was set to 80.0 in the EDM paper [1]; a reasonable + range is [0.2, 80.0]. + sigma_data (`float`, *optional*, defaults to 0.5): + The standard deviation of the data distribution. This is set to 0.5 in the EDM paper [1]. + sigma_schedule (`str`, *optional*, defaults to `karras`): + Sigma schedule to compute the `sigmas`. By default, we the schedule introduced in the EDM paper + (https://huggingface.co/papers/2206.00364). Other acceptable value is "exponential". The exponential + schedule was incorporated in this model: https://huggingface.co/stabilityai/cosxl. + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + solver_order (`int`, defaults to 2): + The DPMSolver order which can be `1` or `2` or `3`. It is recommended to use `solver_order=2` for guided + sampling, and `solver_order=3` for unconditional sampling. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + thresholding (`bool`, defaults to `False`): + Whether to use the "dynamic thresholding" method. This is unsuitable for latent-space diffusion models such + as Stable Diffusion. + dynamic_thresholding_ratio (`float`, defaults to 0.995): + The ratio for the dynamic thresholding method. Valid only when `thresholding=True`. + sample_max_value (`float`, defaults to 1.0): + The threshold value for dynamic thresholding. Valid only when `thresholding=True` and + `algorithm_type="dpmsolver++"`. + algorithm_type (`str`, defaults to `dpmsolver++`): + Algorithm type for the solver; can be `dpmsolver++` or `sde-dpmsolver++`. The `dpmsolver++` type implements + the algorithms in the [DPMSolver++](https://huggingface.co/papers/2211.01095) paper. It is recommended to + use `dpmsolver++` or `sde-dpmsolver++` with `solver_order=2` for guided sampling like in Stable Diffusion. + solver_type (`str`, defaults to `midpoint`): + Solver type for the second-order solver; can be `midpoint` or `heun`. The solver type slightly affects the + sample quality, especially for a small number of steps. It is recommended to use `midpoint` solvers. + lower_order_final (`bool`, defaults to `True`): + Whether to use lower-order solvers in the final steps. Only valid for < 15 inference steps. This can + stabilize the sampling of DPMSolver for steps < 15, especially for steps <= 10. + euler_at_final (`bool`, defaults to `False`): + Whether to use Euler's method in the final step. It is a trade-off between numerical stability and detail + richness. This can stabilize the sampling of the SDE variant of DPMSolver for small number of inference + steps, but sometimes may result in blurring. + final_sigmas_type (`str`, defaults to `"zero"`): + The final `sigma` value for the noise schedule during the sampling process. If `"sigma_min"`, the final + sigma is the same as the last sigma in the training schedule. If `zero`, the final sigma is set to 0. + """ + + _compatibles = [] + order = 1 + + @register_to_config + def __init__( + self, + sigma_min: float = 0.002, + sigma_max: float = 80.0, + sigma_data: float = 0.5, + sigma_schedule: str = "karras", + num_train_timesteps: int = 1000, + prediction_type: str = "epsilon", + rho: float = 7.0, + solver_order: int = 2, + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + sample_max_value: float = 1.0, + algorithm_type: str = "dpmsolver++", + solver_type: str = "midpoint", + lower_order_final: bool = True, + euler_at_final: bool = False, + final_sigmas_type: Optional[str] = "zero", # "zero", "sigma_min" + ): + # settings for DPM-Solver + if algorithm_type not in ["dpmsolver++", "sde-dpmsolver++"]: + if algorithm_type == "deis": + self.register_to_config(algorithm_type="dpmsolver++") + else: + raise NotImplementedError(f"{algorithm_type} is not implemented for {self.__class__}") + + if solver_type not in ["midpoint", "heun"]: + if solver_type in ["logrho", "bh1", "bh2"]: + self.register_to_config(solver_type="midpoint") + else: + raise NotImplementedError(f"{solver_type} is not implemented for {self.__class__}") + + if algorithm_type not in ["dpmsolver++", "sde-dpmsolver++"] and final_sigmas_type == "zero": + raise ValueError( + f"`final_sigmas_type` {final_sigmas_type} is not supported for `algorithm_type` {algorithm_type}. Please choose `sigma_min` instead." + ) + + ramp = torch.linspace(0, 1, num_train_timesteps) + if sigma_schedule == "karras": + sigmas = self._compute_karras_sigmas(ramp) + elif sigma_schedule == "exponential": + sigmas = self._compute_exponential_sigmas(ramp) + + self.timesteps = self.precondition_noise(sigmas) + + self.sigmas = torch.cat([sigmas, torch.zeros(1, device=sigmas.device)]) + + # setable values + self.num_inference_steps = None + self.model_outputs = [None] * solver_order + self.lower_order_nums = 0 + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def init_noise_sigma(self): + # standard deviation of the initial noise distribution + return (self.config.sigma_max**2 + 1) ** 0.5 + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + # Copied from diffusers.schedulers.scheduling_edm_euler.EDMEulerScheduler.precondition_inputs + def precondition_inputs(self, sample, sigma): + c_in = self._get_conditioning_c_in(sigma) + scaled_sample = sample * c_in + return scaled_sample + + # Copied from diffusers.schedulers.scheduling_edm_euler.EDMEulerScheduler.precondition_noise + def precondition_noise(self, sigma): + if not isinstance(sigma, torch.Tensor): + sigma = torch.tensor([sigma]) + + c_noise = 0.25 * torch.log(sigma) + + return c_noise + + # Copied from diffusers.schedulers.scheduling_edm_euler.EDMEulerScheduler.precondition_outputs + def precondition_outputs(self, sample, model_output, sigma): + sigma_data = self.config.sigma_data + c_skip = sigma_data**2 / (sigma**2 + sigma_data**2) + + if self.config.prediction_type == "epsilon": + c_out = sigma * sigma_data / (sigma**2 + sigma_data**2) ** 0.5 + elif self.config.prediction_type == "v_prediction": + c_out = -sigma * sigma_data / (sigma**2 + sigma_data**2) ** 0.5 + else: + raise ValueError(f"Prediction type {self.config.prediction_type} is not supported.") + + denoised = c_skip * sample + c_out * model_output + + return denoised + + # Copied from diffusers.schedulers.scheduling_edm_euler.EDMEulerScheduler.scale_model_input + def scale_model_input(self, sample: torch.Tensor, timestep: Union[float, torch.Tensor]) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. Scales the denoising model input by `(sigma**2 + 1) ** 0.5` to match the Euler algorithm. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + if self.step_index is None: + self._init_step_index(timestep) + + sigma = self.sigmas[self.step_index] + sample = self.precondition_inputs(sample, sigma) + + self.is_scale_input_called = True + return sample + + def set_timesteps(self, num_inference_steps: int = None, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + + self.num_inference_steps = num_inference_steps + + ramp = torch.linspace(0, 1, self.num_inference_steps) + if self.config.sigma_schedule == "karras": + sigmas = self._compute_karras_sigmas(ramp) + elif self.config.sigma_schedule == "exponential": + sigmas = self._compute_exponential_sigmas(ramp) + + sigmas = sigmas.to(dtype=torch.float32, device=device) + self.timesteps = self.precondition_noise(sigmas) + + if self.config.final_sigmas_type == "sigma_min": + sigma_last = self.config.sigma_min + elif self.config.final_sigmas_type == "zero": + sigma_last = 0 + else: + raise ValueError( + f"`final_sigmas_type` must be one of 'zero', or 'sigma_min', but got {self.config.final_sigmas_type}" + ) + + self.sigmas = torch.cat([sigmas, torch.tensor([sigma_last], dtype=torch.float32, device=device)]) + + self.model_outputs = [ + None, + ] * self.config.solver_order + self.lower_order_nums = 0 + + # add an index counter for schedulers that allow duplicated timesteps + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Copied from diffusers.schedulers.scheduling_edm_euler.EDMEulerScheduler._compute_karras_sigmas + def _compute_karras_sigmas(self, ramp, sigma_min=None, sigma_max=None) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + sigma_min = sigma_min or self.config.sigma_min + sigma_max = sigma_max or self.config.sigma_max + + rho = self.config.rho + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_edm_euler.EDMEulerScheduler._compute_exponential_sigmas + def _compute_exponential_sigmas(self, ramp, sigma_min=None, sigma_max=None) -> torch.Tensor: + """Implementation closely follows k-diffusion. + + https://github.com/crowsonkb/k-diffusion/blob/6ab5146d4a5ef63901326489f31f1d8e7dd36b48/k_diffusion/sampling.py#L26 + """ + sigma_min = sigma_min or self.config.sigma_min + sigma_max = sigma_max or self.config.sigma_max + sigmas = torch.linspace(math.log(sigma_min), math.log(sigma_max), len(ramp)).exp().flip(0) + return sigmas + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler._threshold_sample + def _threshold_sample(self, sample: torch.Tensor) -> torch.Tensor: + """ + "Dynamic thresholding: At each sampling step we set s to a certain percentile absolute pixel value in xt0 (the + prediction of x_0 at timestep t), and if s > 1, then we threshold xt0 to the range [-s, s] and then divide by + s. Dynamic thresholding pushes saturated pixels (those near -1 and 1) inwards, thereby actively preventing + pixels from saturation at each step. We find that dynamic thresholding results in significantly better + photorealism as well as better image-text alignment, especially when using very large guidance weights." + + https://huggingface.co/papers/2205.11487 + """ + dtype = sample.dtype + batch_size, channels, *remaining_dims = sample.shape + + if dtype not in (torch.float32, torch.float64): + sample = sample.float() # upcast for quantile calculation, and clamp not implemented for cpu half + + # Flatten sample for doing quantile calculation along each image + sample = sample.reshape(batch_size, channels * np.prod(remaining_dims)) + + abs_sample = sample.abs() # "a certain percentile absolute pixel value" + + s = torch.quantile(abs_sample, self.config.dynamic_thresholding_ratio, dim=1) + s = torch.clamp( + s, min=1, max=self.config.sample_max_value + ) # When clamped to min=1, equivalent to standard clipping to [-1, 1] + s = s.unsqueeze(1) # (batch_size, 1) because clamp will broadcast along dim=0 + sample = torch.clamp(sample, -s, s) / s # "we threshold xt0 to the range [-s, s] and then divide by s" + + sample = sample.reshape(batch_size, channels, *remaining_dims) + sample = sample.to(dtype) + + return sample + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._sigma_to_t + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + def _sigma_to_alpha_sigma_t(self, sigma): + alpha_t = torch.tensor(1) # Inputs are pre-scaled before going into unet, so alpha_t = 1 + sigma_t = sigma + + return alpha_t, sigma_t + + def convert_model_output( + self, + model_output: torch.Tensor, + sample: torch.Tensor = None, + ) -> torch.Tensor: + """ + Convert the model output to the corresponding type the DPMSolver/DPMSolver++ algorithm needs. DPM-Solver is + designed to discretize an integral of the noise prediction model, and DPM-Solver++ is designed to discretize an + integral of the data prediction model. + + + + The algorithm and model type are decoupled. You can use either DPMSolver or DPMSolver++ for both noise + prediction and data prediction models. + + + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The converted model output. + """ + sigma = self.sigmas[self.step_index] + x0_pred = self.precondition_outputs(sample, model_output, sigma) + + if self.config.thresholding: + x0_pred = self._threshold_sample(x0_pred) + + return x0_pred + + def dpm_solver_first_order_update( + self, + model_output: torch.Tensor, + sample: torch.Tensor = None, + noise: Optional[torch.Tensor] = None, + ) -> torch.Tensor: + """ + One step for the first-order DPMSolver (equivalent to DDIM). + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + sigma_t, sigma_s = self.sigmas[self.step_index + 1], self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s, sigma_s = self._sigma_to_alpha_sigma_t(sigma_s) + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s = torch.log(alpha_s) - torch.log(sigma_s) + + h = lambda_t - lambda_s + if self.config.algorithm_type == "dpmsolver++": + x_t = (sigma_t / sigma_s) * sample - (alpha_t * (torch.exp(-h) - 1.0)) * model_output + elif self.config.algorithm_type == "sde-dpmsolver++": + assert noise is not None + x_t = ( + (sigma_t / sigma_s * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * model_output + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + + return x_t + + def multistep_dpm_solver_second_order_update( + self, + model_output_list: List[torch.Tensor], + sample: torch.Tensor = None, + noise: Optional[torch.Tensor] = None, + ) -> torch.Tensor: + """ + One step for the second-order multistep DPMSolver. + + Args: + model_output_list (`List[torch.Tensor]`): + The direct outputs from learned diffusion model at current and latter timesteps. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + sigma_t, sigma_s0, sigma_s1 = ( + self.sigmas[self.step_index + 1], + self.sigmas[self.step_index], + self.sigmas[self.step_index - 1], + ) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + alpha_s1, sigma_s1 = self._sigma_to_alpha_sigma_t(sigma_s1) + + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s0 = torch.log(alpha_s0) - torch.log(sigma_s0) + lambda_s1 = torch.log(alpha_s1) - torch.log(sigma_s1) + + m0, m1 = model_output_list[-1], model_output_list[-2] + + h, h_0 = lambda_t - lambda_s0, lambda_s0 - lambda_s1 + r0 = h_0 / h + D0, D1 = m0, (1.0 / r0) * (m0 - m1) + if self.config.algorithm_type == "dpmsolver++": + # See https://huggingface.co/papers/2211.01095 for detailed derivations + if self.config.solver_type == "midpoint": + x_t = ( + (sigma_t / sigma_s0) * sample + - (alpha_t * (torch.exp(-h) - 1.0)) * D0 + - 0.5 * (alpha_t * (torch.exp(-h) - 1.0)) * D1 + ) + elif self.config.solver_type == "heun": + x_t = ( + (sigma_t / sigma_s0) * sample + - (alpha_t * (torch.exp(-h) - 1.0)) * D0 + + (alpha_t * ((torch.exp(-h) - 1.0) / h + 1.0)) * D1 + ) + elif self.config.algorithm_type == "sde-dpmsolver++": + assert noise is not None + if self.config.solver_type == "midpoint": + x_t = ( + (sigma_t / sigma_s0 * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * D0 + + 0.5 * (alpha_t * (1 - torch.exp(-2.0 * h))) * D1 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + elif self.config.solver_type == "heun": + x_t = ( + (sigma_t / sigma_s0 * torch.exp(-h)) * sample + + (alpha_t * (1 - torch.exp(-2.0 * h))) * D0 + + (alpha_t * ((1.0 - torch.exp(-2.0 * h)) / (-2.0 * h) + 1.0)) * D1 + + sigma_t * torch.sqrt(1.0 - torch.exp(-2 * h)) * noise + ) + + return x_t + + def multistep_dpm_solver_third_order_update( + self, + model_output_list: List[torch.Tensor], + sample: torch.Tensor = None, + ) -> torch.Tensor: + """ + One step for the third-order multistep DPMSolver. + + Args: + model_output_list (`List[torch.Tensor]`): + The direct outputs from learned diffusion model at current and latter timesteps. + sample (`torch.Tensor`): + A current instance of a sample created by diffusion process. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + sigma_t, sigma_s0, sigma_s1, sigma_s2 = ( + self.sigmas[self.step_index + 1], + self.sigmas[self.step_index], + self.sigmas[self.step_index - 1], + self.sigmas[self.step_index - 2], + ) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + alpha_s1, sigma_s1 = self._sigma_to_alpha_sigma_t(sigma_s1) + alpha_s2, sigma_s2 = self._sigma_to_alpha_sigma_t(sigma_s2) + + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s0 = torch.log(alpha_s0) - torch.log(sigma_s0) + lambda_s1 = torch.log(alpha_s1) - torch.log(sigma_s1) + lambda_s2 = torch.log(alpha_s2) - torch.log(sigma_s2) + + m0, m1, m2 = model_output_list[-1], model_output_list[-2], model_output_list[-3] + + h, h_0, h_1 = lambda_t - lambda_s0, lambda_s0 - lambda_s1, lambda_s1 - lambda_s2 + r0, r1 = h_0 / h, h_1 / h + D0 = m0 + D1_0, D1_1 = (1.0 / r0) * (m0 - m1), (1.0 / r1) * (m1 - m2) + D1 = D1_0 + (r0 / (r0 + r1)) * (D1_0 - D1_1) + D2 = (1.0 / (r0 + r1)) * (D1_0 - D1_1) + if self.config.algorithm_type == "dpmsolver++": + # See https://huggingface.co/papers/2206.00927 for detailed derivations + x_t = ( + (sigma_t / sigma_s0) * sample + - (alpha_t * (torch.exp(-h) - 1.0)) * D0 + + (alpha_t * ((torch.exp(-h) - 1.0) / h + 1.0)) * D1 + - (alpha_t * ((torch.exp(-h) - 1.0 + h) / h**2 - 0.5)) * D2 + ) + + return x_t + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + index_candidates = (schedule_timesteps == timestep).nonzero() + + if len(index_candidates) == 0: + step_index = len(self.timesteps) - 1 + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + elif len(index_candidates) > 1: + step_index = index_candidates[1].item() + else: + step_index = index_candidates[0].item() + + return step_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler._init_step_index + def _init_step_index(self, timestep): + """ + Initialize the step_index counter for the scheduler. + """ + + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.Tensor, + timestep: Union[int, torch.Tensor], + sample: torch.Tensor, + generator=None, + return_dict: bool = True, + ) -> Union[SchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the sample with + the multistep DPMSolver. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_utils.SchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + if self.step_index is None: + self._init_step_index(timestep) + + # Improve numerical stability for small number of steps + lower_order_final = (self.step_index == len(self.timesteps) - 1) and ( + self.config.euler_at_final + or (self.config.lower_order_final and len(self.timesteps) < 15) + or self.config.final_sigmas_type == "zero" + ) + lower_order_second = ( + (self.step_index == len(self.timesteps) - 2) and self.config.lower_order_final and len(self.timesteps) < 15 + ) + + model_output = self.convert_model_output(model_output, sample=sample) + for i in range(self.config.solver_order - 1): + self.model_outputs[i] = self.model_outputs[i + 1] + self.model_outputs[-1] = model_output + + if self.config.algorithm_type == "sde-dpmsolver++": + noise = randn_tensor( + model_output.shape, generator=generator, device=model_output.device, dtype=model_output.dtype + ) + else: + noise = None + + if self.config.solver_order == 1 or self.lower_order_nums < 1 or lower_order_final: + prev_sample = self.dpm_solver_first_order_update(model_output, sample=sample, noise=noise) + elif self.config.solver_order == 2 or self.lower_order_nums < 2 or lower_order_second: + prev_sample = self.multistep_dpm_solver_second_order_update(self.model_outputs, sample=sample, noise=noise) + else: + prev_sample = self.multistep_dpm_solver_third_order_update(self.model_outputs, sample=sample) + + if self.lower_order_nums < self.config.solver_order: + self.lower_order_nums += 1 + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return (prev_sample,) + + return SchedulerOutput(prev_sample=prev_sample) + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.Tensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # self.begin_index is None when scheduler is used for training, or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + noisy_samples = original_samples + noise * sigma + return noisy_samples + + # Copied from diffusers.schedulers.scheduling_edm_euler.EDMEulerScheduler._get_conditioning_c_in + def _get_conditioning_c_in(self, sigma): + c_in = 1 / ((sigma**2 + self.config.sigma_data**2) ** 0.5) + return c_in + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_edm_euler.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_edm_euler.py new file mode 100644 index 0000000000000000000000000000000000000000..d5c89306e8056b9838c520c846e53dc68c0e0f9e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_edm_euler.py @@ -0,0 +1,448 @@ +# Copyright 2024 Katherine Crowson and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput, logging +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import SchedulerMixin + + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->EulerDiscrete +class EDMEulerSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +class EDMEulerScheduler(SchedulerMixin, ConfigMixin): + """ + Implements the Euler scheduler in EDM formulation as presented in Karras et al. 2022 [1]. + + [1] Karras, Tero, et al. "Elucidating the Design Space of Diffusion-Based Generative Models." + https://huggingface.co/papers/2206.00364 + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + sigma_min (`float`, *optional*, defaults to 0.002): + Minimum noise magnitude in the sigma schedule. This was set to 0.002 in the EDM paper [1]; a reasonable + range is [0, 10]. + sigma_max (`float`, *optional*, defaults to 80.0): + Maximum noise magnitude in the sigma schedule. This was set to 80.0 in the EDM paper [1]; a reasonable + range is [0.2, 80.0]. + sigma_data (`float`, *optional*, defaults to 0.5): + The standard deviation of the data distribution. This is set to 0.5 in the EDM paper [1]. + sigma_schedule (`str`, *optional*, defaults to `karras`): + Sigma schedule to compute the `sigmas`. By default, we the schedule introduced in the EDM paper + (https://huggingface.co/papers/2206.00364). Other acceptable value is "exponential". The exponential + schedule was incorporated in this model: https://huggingface.co/stabilityai/cosxl. + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + rho (`float`, *optional*, defaults to 7.0): + The rho parameter used for calculating the Karras sigma schedule, which is set to 7.0 in the EDM paper [1]. + final_sigmas_type (`str`, defaults to `"zero"`): + The final `sigma` value for the noise schedule during the sampling process. If `"sigma_min"`, the final + sigma is the same as the last sigma in the training schedule. If `zero`, the final sigma is set to 0. + """ + + _compatibles = [] + order = 1 + + @register_to_config + def __init__( + self, + sigma_min: float = 0.002, + sigma_max: float = 80.0, + sigma_data: float = 0.5, + sigma_schedule: str = "karras", + num_train_timesteps: int = 1000, + prediction_type: str = "epsilon", + rho: float = 7.0, + final_sigmas_type: str = "zero", # can be "zero" or "sigma_min" + ): + if sigma_schedule not in ["karras", "exponential"]: + raise ValueError(f"Wrong value for provided for `{sigma_schedule=}`.`") + + # setable values + self.num_inference_steps = None + + sigmas_dtype = torch.float32 if torch.backends.mps.is_available() else torch.float64 + sigmas = torch.arange(num_train_timesteps + 1, dtype=sigmas_dtype) / num_train_timesteps + if sigma_schedule == "karras": + sigmas = self._compute_karras_sigmas(sigmas) + elif sigma_schedule == "exponential": + sigmas = self._compute_exponential_sigmas(sigmas) + sigmas = sigmas.to(torch.float32) + + self.timesteps = self.precondition_noise(sigmas) + + if self.config.final_sigmas_type == "sigma_min": + sigma_last = sigmas[-1] + elif self.config.final_sigmas_type == "zero": + sigma_last = 0 + else: + raise ValueError( + f"`final_sigmas_type` must be one of 'zero', or 'sigma_min', but got {self.config.final_sigmas_type}" + ) + + self.sigmas = torch.cat([sigmas, torch.full((1,), fill_value=sigma_last, device=sigmas.device)]) + + self.is_scale_input_called = False + + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def init_noise_sigma(self): + # standard deviation of the initial noise distribution + return (self.config.sigma_max**2 + 1) ** 0.5 + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def precondition_inputs(self, sample, sigma): + c_in = self._get_conditioning_c_in(sigma) + scaled_sample = sample * c_in + return scaled_sample + + def precondition_noise(self, sigma): + if not isinstance(sigma, torch.Tensor): + sigma = torch.tensor([sigma]) + + c_noise = 0.25 * torch.log(sigma) + + return c_noise + + def precondition_outputs(self, sample, model_output, sigma): + sigma_data = self.config.sigma_data + c_skip = sigma_data**2 / (sigma**2 + sigma_data**2) + + if self.config.prediction_type == "epsilon": + c_out = sigma * sigma_data / (sigma**2 + sigma_data**2) ** 0.5 + elif self.config.prediction_type == "v_prediction": + c_out = -sigma * sigma_data / (sigma**2 + sigma_data**2) ** 0.5 + else: + raise ValueError(f"Prediction type {self.config.prediction_type} is not supported.") + + denoised = c_skip * sample + c_out * model_output + + return denoised + + def scale_model_input(self, sample: torch.Tensor, timestep: Union[float, torch.Tensor]) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. Scales the denoising model input by `(sigma**2 + 1) ** 0.5` to match the Euler algorithm. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + if self.step_index is None: + self._init_step_index(timestep) + + sigma = self.sigmas[self.step_index] + sample = self.precondition_inputs(sample, sigma) + + self.is_scale_input_called = True + return sample + + def set_timesteps( + self, + num_inference_steps: int = None, + device: Union[str, torch.device] = None, + sigmas: Optional[Union[torch.Tensor, List[float]]] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + sigmas (`Union[torch.Tensor, List[float]]`, *optional*): + Custom sigmas to use for the denoising process. If not defined, the default behavior when + `num_inference_steps` is passed will be used. + """ + self.num_inference_steps = num_inference_steps + + sigmas_dtype = torch.float32 if torch.backends.mps.is_available() else torch.float64 + if sigmas is None: + sigmas = torch.linspace(0, 1, self.num_inference_steps, dtype=sigmas_dtype) + elif isinstance(sigmas, float): + sigmas = torch.tensor(sigmas, dtype=sigmas_dtype) + else: + sigmas = sigmas.to(sigmas_dtype) + if self.config.sigma_schedule == "karras": + sigmas = self._compute_karras_sigmas(sigmas) + elif self.config.sigma_schedule == "exponential": + sigmas = self._compute_exponential_sigmas(sigmas) + sigmas = sigmas.to(dtype=torch.float32, device=device) + + self.timesteps = self.precondition_noise(sigmas) + + if self.config.final_sigmas_type == "sigma_min": + sigma_last = sigmas[-1] + elif self.config.final_sigmas_type == "zero": + sigma_last = 0 + else: + raise ValueError( + f"`final_sigmas_type` must be one of 'zero', or 'sigma_min', but got {self.config.final_sigmas_type}" + ) + + self.sigmas = torch.cat([sigmas, torch.full((1,), fill_value=sigma_last, device=sigmas.device)]) + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Taken from https://github.com/crowsonkb/k-diffusion/blob/686dbad0f39640ea25c8a8c6a6e56bb40eacefa2/k_diffusion/sampling.py#L17 + def _compute_karras_sigmas(self, ramp, sigma_min=None, sigma_max=None) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + sigma_min = sigma_min or self.config.sigma_min + sigma_max = sigma_max or self.config.sigma_max + + rho = self.config.rho + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + def _compute_exponential_sigmas(self, ramp, sigma_min=None, sigma_max=None) -> torch.Tensor: + """Implementation closely follows k-diffusion. + + https://github.com/crowsonkb/k-diffusion/blob/6ab5146d4a5ef63901326489f31f1d8e7dd36b48/k_diffusion/sampling.py#L26 + """ + sigma_min = sigma_min or self.config.sigma_min + sigma_max = sigma_max or self.config.sigma_max + sigmas = torch.linspace(math.log(sigma_min), math.log(sigma_max), len(ramp)).exp().flip(0) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._init_step_index + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.Tensor, + timestep: Union[float, torch.Tensor], + sample: torch.Tensor, + s_churn: float = 0.0, + s_tmin: float = 0.0, + s_tmax: float = float("inf"), + s_noise: float = 1.0, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + pred_original_sample: Optional[torch.Tensor] = None, + ) -> Union[EDMEulerSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + s_churn (`float`): + s_tmin (`float`): + s_tmax (`float`): + s_noise (`float`, defaults to 1.0): + Scaling factor for noise added to the sample. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_euler_discrete.EDMEulerSchedulerOutput`] or tuple. + + Returns: + [`~schedulers.scheduling_euler_discrete.EDMEulerSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_euler_discrete.EDMEulerSchedulerOutput`] is + returned, otherwise a tuple is returned where the first element is the sample tensor. + """ + + if isinstance(timestep, (int, torch.IntTensor, torch.LongTensor)): + raise ValueError( + ( + "Passing integer indices (e.g. from `enumerate(timesteps)`) as timesteps to" + " `EDMEulerScheduler.step()` is not supported. Make sure to pass" + " one of the `scheduler.timesteps` as a timestep." + ), + ) + + if not self.is_scale_input_called: + logger.warning( + "The `scale_model_input` function should be called before `step` to ensure correct denoising. " + "See `StableDiffusionPipeline` for a usage example." + ) + + if self.step_index is None: + self._init_step_index(timestep) + + # Upcast to avoid precision issues when computing prev_sample + sample = sample.to(torch.float32) + + sigma = self.sigmas[self.step_index] + + gamma = min(s_churn / (len(self.sigmas) - 1), 2**0.5 - 1) if s_tmin <= sigma <= s_tmax else 0.0 + + sigma_hat = sigma * (gamma + 1) + + if gamma > 0: + noise = randn_tensor( + model_output.shape, dtype=model_output.dtype, device=model_output.device, generator=generator + ) + eps = noise * s_noise + sample = sample + eps * (sigma_hat**2 - sigma**2) ** 0.5 + + # 1. compute predicted original sample (x_0) from sigma-scaled predicted noise + if pred_original_sample is None: + pred_original_sample = self.precondition_outputs(sample, model_output, sigma_hat) + + # 2. Convert to an ODE derivative + derivative = (sample - pred_original_sample) / sigma_hat + + dt = self.sigmas[self.step_index + 1] - sigma_hat + + prev_sample = sample + derivative * dt + + # Cast sample back to model compatible dtype + prev_sample = prev_sample.to(model_output.dtype) + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return ( + prev_sample, + pred_original_sample, + ) + + return EDMEulerSchedulerOutput(prev_sample=prev_sample, pred_original_sample=pred_original_sample) + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.Tensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # self.begin_index is None when scheduler is used for training, or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + noisy_samples = original_samples + noise * sigma + return noisy_samples + + def _get_conditioning_c_in(self, sigma): + c_in = 1 / ((sigma**2 + self.config.sigma_data**2) ** 0.5) + return c_in + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_euler_ancestral_discrete.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_euler_ancestral_discrete.py new file mode 100644 index 0000000000000000000000000000000000000000..0b6f8b817c45402fde1f23ea874bb453f34db5c3 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_euler_ancestral_discrete.py @@ -0,0 +1,482 @@ +# Copyright 2024 Katherine Crowson and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput, logging +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin + + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->EulerAncestralDiscrete +class EulerAncestralDiscreteSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +# Copied from diffusers.schedulers.scheduling_ddim.rescale_zero_terminal_snr +def rescale_zero_terminal_snr(betas): + """ + Rescales betas to have zero terminal SNR Based on https://huggingface.co/papers/2305.08891 (Algorithm 1) + + + Args: + betas (`torch.Tensor`): + the betas that the scheduler is being initialized with. + + Returns: + `torch.Tensor`: rescaled betas with zero terminal SNR + """ + # Convert betas to alphas_bar_sqrt + alphas = 1.0 - betas + alphas_cumprod = torch.cumprod(alphas, dim=0) + alphas_bar_sqrt = alphas_cumprod.sqrt() + + # Store old values. + alphas_bar_sqrt_0 = alphas_bar_sqrt[0].clone() + alphas_bar_sqrt_T = alphas_bar_sqrt[-1].clone() + + # Shift so the last timestep is zero. + alphas_bar_sqrt -= alphas_bar_sqrt_T + + # Scale so the first timestep is back to the old value. + alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T) + + # Convert alphas_bar_sqrt to betas + alphas_bar = alphas_bar_sqrt**2 # Revert sqrt + alphas = alphas_bar[1:] / alphas_bar[:-1] # Revert cumprod + alphas = torch.cat([alphas_bar[0:1], alphas]) + betas = 1 - alphas + + return betas + + +class EulerAncestralDiscreteScheduler(SchedulerMixin, ConfigMixin): + """ + Ancestral sampling with Euler method steps. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear` or `scaled_linear`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + rescale_betas_zero_snr (`bool`, defaults to `False`): + Whether to rescale the betas to have zero terminal SNR. This enables the model to generate very bright and + dark samples instead of limiting it to samples with medium brightness. Loosely related to + [`--offset_noise`](https://github.com/huggingface/diffusers/blob/74fd735eb073eb1d774b1ab4154a0876eb82f055/examples/dreambooth/train_dreambooth.py#L506). + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + prediction_type: str = "epsilon", + timestep_spacing: str = "linspace", + steps_offset: int = 0, + rescale_betas_zero_snr: bool = False, + ): + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + if rescale_betas_zero_snr: + self.betas = rescale_zero_terminal_snr(self.betas) + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + if rescale_betas_zero_snr: + # Close to 0 without being 0 so first sigma is not inf + # FP16 smallest positive subnormal works well here + self.alphas_cumprod[-1] = 2**-24 + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + sigmas = np.concatenate([sigmas[::-1], [0.0]]).astype(np.float32) + self.sigmas = torch.from_numpy(sigmas) + + # setable values + self.num_inference_steps = None + timesteps = np.linspace(0, num_train_timesteps - 1, num_train_timesteps, dtype=float)[::-1].copy() + self.timesteps = torch.from_numpy(timesteps) + self.is_scale_input_called = False + + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def init_noise_sigma(self): + # standard deviation of the initial noise distribution + if self.config.timestep_spacing in ["linspace", "trailing"]: + return self.sigmas.max() + + return (self.sigmas.max() ** 2 + 1) ** 0.5 + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def scale_model_input(self, sample: torch.Tensor, timestep: Union[float, torch.Tensor]) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. Scales the denoising model input by `(sigma**2 + 1) ** 0.5` to match the Euler algorithm. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + + if self.step_index is None: + self._init_step_index(timestep) + + sigma = self.sigmas[self.step_index] + sample = sample / ((sigma**2 + 1) ** 0.5) + self.is_scale_input_called = True + return sample + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + self.num_inference_steps = num_inference_steps + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = np.linspace(0, self.config.num_train_timesteps - 1, num_inference_steps, dtype=np.float32)[ + ::-1 + ].copy() + elif self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.float32) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(self.config.num_train_timesteps, 0, -step_ratio)).round().copy().astype(np.float32) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + sigmas = np.interp(timesteps, np.arange(0, len(sigmas)), sigmas) + sigmas = np.concatenate([sigmas, [0.0]]).astype(np.float32) + self.sigmas = torch.from_numpy(sigmas).to(device=device) + + self.timesteps = torch.from_numpy(timesteps).to(device=device) + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._init_step_index + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.Tensor, + timestep: Union[float, torch.Tensor], + sample: torch.Tensor, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[EulerAncestralDiscreteSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`): + Whether or not to return a + [`~schedulers.scheduling_euler_ancestral_discrete.EulerAncestralDiscreteSchedulerOutput`] or tuple. + + Returns: + [`~schedulers.scheduling_euler_ancestral_discrete.EulerAncestralDiscreteSchedulerOutput`] or `tuple`: + If return_dict is `True`, + [`~schedulers.scheduling_euler_ancestral_discrete.EulerAncestralDiscreteSchedulerOutput`] is returned, + otherwise a tuple is returned where the first element is the sample tensor. + + """ + + if isinstance(timestep, (int, torch.IntTensor, torch.LongTensor)): + raise ValueError( + ( + "Passing integer indices (e.g. from `enumerate(timesteps)`) as timesteps to" + " `EulerDiscreteScheduler.step()` is not supported. Make sure to pass" + " one of the `scheduler.timesteps` as a timestep." + ), + ) + + if not self.is_scale_input_called: + logger.warning( + "The `scale_model_input` function should be called before `step` to ensure correct denoising. " + "See `StableDiffusionPipeline` for a usage example." + ) + + if self.step_index is None: + self._init_step_index(timestep) + + sigma = self.sigmas[self.step_index] + + # Upcast to avoid precision issues when computing prev_sample + sample = sample.to(torch.float32) + + # 1. compute predicted original sample (x_0) from sigma-scaled predicted noise + if self.config.prediction_type == "epsilon": + pred_original_sample = sample - sigma * model_output + elif self.config.prediction_type == "v_prediction": + # * c_out + input * c_skip + pred_original_sample = model_output * (-sigma / (sigma**2 + 1) ** 0.5) + (sample / (sigma**2 + 1)) + elif self.config.prediction_type == "sample": + raise NotImplementedError("prediction_type not implemented yet: sample") + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, or `v_prediction`" + ) + + sigma_from = self.sigmas[self.step_index] + sigma_to = self.sigmas[self.step_index + 1] + sigma_up = (sigma_to**2 * (sigma_from**2 - sigma_to**2) / sigma_from**2) ** 0.5 + sigma_down = (sigma_to**2 - sigma_up**2) ** 0.5 + + # 2. Convert to an ODE derivative + derivative = (sample - pred_original_sample) / sigma + + dt = sigma_down - sigma + + prev_sample = sample + derivative * dt + + device = model_output.device + noise = randn_tensor(model_output.shape, dtype=model_output.dtype, device=device, generator=generator) + + prev_sample = prev_sample + noise * sigma_up + + # Cast sample back to model compatible dtype + prev_sample = prev_sample.to(model_output.dtype) + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return ( + prev_sample, + pred_original_sample, + ) + + return EulerAncestralDiscreteSchedulerOutput( + prev_sample=prev_sample, pred_original_sample=pred_original_sample + ) + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.Tensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # self.begin_index is None when scheduler is used for training, or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + noisy_samples = original_samples + noise * sigma + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_euler_discrete.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_euler_discrete.py new file mode 100644 index 0000000000000000000000000000000000000000..1bade69726db6d5b583cad167578a3de46411b2b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_euler_discrete.py @@ -0,0 +1,757 @@ +# Copyright 2024 Katherine Crowson and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput, is_scipy_available, logging +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin + + +if is_scipy_available(): + import scipy.stats + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->EulerDiscrete +class EulerDiscreteSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +# Copied from diffusers.schedulers.scheduling_ddim.rescale_zero_terminal_snr +def rescale_zero_terminal_snr(betas): + """ + Rescales betas to have zero terminal SNR Based on https://huggingface.co/papers/2305.08891 (Algorithm 1) + + + Args: + betas (`torch.Tensor`): + the betas that the scheduler is being initialized with. + + Returns: + `torch.Tensor`: rescaled betas with zero terminal SNR + """ + # Convert betas to alphas_bar_sqrt + alphas = 1.0 - betas + alphas_cumprod = torch.cumprod(alphas, dim=0) + alphas_bar_sqrt = alphas_cumprod.sqrt() + + # Store old values. + alphas_bar_sqrt_0 = alphas_bar_sqrt[0].clone() + alphas_bar_sqrt_T = alphas_bar_sqrt[-1].clone() + + # Shift so the last timestep is zero. + alphas_bar_sqrt -= alphas_bar_sqrt_T + + # Scale so the first timestep is back to the old value. + alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T) + + # Convert alphas_bar_sqrt to betas + alphas_bar = alphas_bar_sqrt**2 # Revert sqrt + alphas = alphas_bar[1:] / alphas_bar[:-1] # Revert cumprod + alphas = torch.cat([alphas_bar[0:1], alphas]) + betas = 1 - alphas + + return betas + + +class EulerDiscreteScheduler(SchedulerMixin, ConfigMixin): + """ + Euler scheduler. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear` or `scaled_linear`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + interpolation_type(`str`, defaults to `"linear"`, *optional*): + The interpolation type to compute intermediate sigmas for the scheduler denoising steps. Should be on of + `"linear"` or `"log_linear"`. + use_karras_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use Karras sigmas for step sizes in the noise schedule during the sampling process. If `True`, + the sigmas are determined according to a sequence of noise levels {σi}. + use_exponential_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use exponential sigmas for step sizes in the noise schedule during the sampling process. + use_beta_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use beta sigmas for step sizes in the noise schedule during the sampling process. Refer to [Beta + Sampling is All You Need](https://huggingface.co/papers/2407.12173) for more information. + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + rescale_betas_zero_snr (`bool`, defaults to `False`): + Whether to rescale the betas to have zero terminal SNR. This enables the model to generate very bright and + dark samples instead of limiting it to samples with medium brightness. Loosely related to + [`--offset_noise`](https://github.com/huggingface/diffusers/blob/74fd735eb073eb1d774b1ab4154a0876eb82f055/examples/dreambooth/train_dreambooth.py#L506). + final_sigmas_type (`str`, defaults to `"zero"`): + The final `sigma` value for the noise schedule during the sampling process. If `"sigma_min"`, the final + sigma is the same as the last sigma in the training schedule. If `zero`, the final sigma is set to 0. + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + prediction_type: str = "epsilon", + interpolation_type: str = "linear", + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + sigma_min: Optional[float] = None, + sigma_max: Optional[float] = None, + timestep_spacing: str = "linspace", + timestep_type: str = "discrete", # can be "discrete" or "continuous" + steps_offset: int = 0, + rescale_betas_zero_snr: bool = False, + final_sigmas_type: str = "zero", # can be "zero" or "sigma_min" + ): + if self.config.use_beta_sigmas and not is_scipy_available(): + raise ImportError("Make sure to install scipy if you want to use beta sigmas.") + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + if rescale_betas_zero_snr: + self.betas = rescale_zero_terminal_snr(self.betas) + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + if rescale_betas_zero_snr: + # Close to 0 without being 0 so first sigma is not inf + # FP16 smallest positive subnormal works well here + self.alphas_cumprod[-1] = 2**-24 + + sigmas = (((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5).flip(0) + timesteps = np.linspace(0, num_train_timesteps - 1, num_train_timesteps, dtype=float)[::-1].copy() + timesteps = torch.from_numpy(timesteps).to(dtype=torch.float32) + + # setable values + self.num_inference_steps = None + + # TODO: Support the full EDM scalings for all prediction types and timestep types + if timestep_type == "continuous" and prediction_type == "v_prediction": + self.timesteps = torch.Tensor([0.25 * sigma.log() for sigma in sigmas]) + else: + self.timesteps = timesteps + + self.sigmas = torch.cat([sigmas, torch.zeros(1, device=sigmas.device)]) + + self.is_scale_input_called = False + self.use_karras_sigmas = use_karras_sigmas + self.use_exponential_sigmas = use_exponential_sigmas + self.use_beta_sigmas = use_beta_sigmas + + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def init_noise_sigma(self): + # standard deviation of the initial noise distribution + max_sigma = max(self.sigmas) if isinstance(self.sigmas, list) else self.sigmas.max() + if self.config.timestep_spacing in ["linspace", "trailing"]: + return max_sigma + + return (max_sigma**2 + 1) ** 0.5 + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def scale_model_input(self, sample: torch.Tensor, timestep: Union[float, torch.Tensor]) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. Scales the denoising model input by `(sigma**2 + 1) ** 0.5` to match the Euler algorithm. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + if self.step_index is None: + self._init_step_index(timestep) + + sigma = self.sigmas[self.step_index] + sample = sample / ((sigma**2 + 1) ** 0.5) + + self.is_scale_input_called = True + return sample + + def set_timesteps( + self, + num_inference_steps: int = None, + device: Union[str, torch.device] = None, + timesteps: Optional[List[int]] = None, + sigmas: Optional[List[float]] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + timesteps (`List[int]`, *optional*): + Custom timesteps used to support arbitrary timesteps schedule. If `None`, timesteps will be generated + based on the `timestep_spacing` attribute. If `timesteps` is passed, `num_inference_steps` and `sigmas` + must be `None`, and `timestep_spacing` attribute will be ignored. + sigmas (`List[float]`, *optional*): + Custom sigmas used to support arbitrary timesteps schedule schedule. If `None`, timesteps and sigmas + will be generated based on the relevant scheduler attributes. If `sigmas` is passed, + `num_inference_steps` and `timesteps` must be `None`, and the timesteps will be generated based on the + custom sigmas schedule. + """ + + if timesteps is not None and sigmas is not None: + raise ValueError("Only one of `timesteps` or `sigmas` should be set.") + if num_inference_steps is None and timesteps is None and sigmas is None: + raise ValueError("Must pass exactly one of `num_inference_steps` or `timesteps` or `sigmas.") + if num_inference_steps is not None and (timesteps is not None or sigmas is not None): + raise ValueError("Can only pass one of `num_inference_steps` or `timesteps` or `sigmas`.") + if timesteps is not None and self.config.use_karras_sigmas: + raise ValueError("Cannot set `timesteps` with `config.use_karras_sigmas = True`.") + if timesteps is not None and self.config.use_exponential_sigmas: + raise ValueError("Cannot set `timesteps` with `config.use_exponential_sigmas = True`.") + if timesteps is not None and self.config.use_beta_sigmas: + raise ValueError("Cannot set `timesteps` with `config.use_beta_sigmas = True`.") + if ( + timesteps is not None + and self.config.timestep_type == "continuous" + and self.config.prediction_type == "v_prediction" + ): + raise ValueError( + "Cannot set `timesteps` with `config.timestep_type = 'continuous'` and `config.prediction_type = 'v_prediction'`." + ) + + if num_inference_steps is None: + num_inference_steps = len(timesteps) if timesteps is not None else len(sigmas) - 1 + self.num_inference_steps = num_inference_steps + + if sigmas is not None: + log_sigmas = np.log(np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5)) + sigmas = np.array(sigmas).astype(np.float32) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas[:-1]]) + + else: + if timesteps is not None: + timesteps = np.array(timesteps).astype(np.float32) + else: + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = np.linspace( + 0, self.config.num_train_timesteps - 1, num_inference_steps, dtype=np.float32 + )[::-1].copy() + elif self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = ( + (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.float32) + ) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = ( + (np.arange(self.config.num_train_timesteps, 0, -step_ratio)).round().copy().astype(np.float32) + ) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + log_sigmas = np.log(sigmas) + if self.config.interpolation_type == "linear": + sigmas = np.interp(timesteps, np.arange(0, len(sigmas)), sigmas) + elif self.config.interpolation_type == "log_linear": + sigmas = torch.linspace(np.log(sigmas[-1]), np.log(sigmas[0]), num_inference_steps + 1).exp().numpy() + else: + raise ValueError( + f"{self.config.interpolation_type} is not implemented. Please specify interpolation_type to either" + " 'linear' or 'log_linear'" + ) + + if self.config.use_karras_sigmas: + sigmas = self._convert_to_karras(in_sigmas=sigmas, num_inference_steps=self.num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + + elif self.config.use_exponential_sigmas: + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + + elif self.config.use_beta_sigmas: + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + + if self.config.final_sigmas_type == "sigma_min": + sigma_last = ((1 - self.alphas_cumprod[0]) / self.alphas_cumprod[0]) ** 0.5 + elif self.config.final_sigmas_type == "zero": + sigma_last = 0 + else: + raise ValueError( + f"`final_sigmas_type` must be one of 'zero', or 'sigma_min', but got {self.config.final_sigmas_type}" + ) + + sigmas = np.concatenate([sigmas, [sigma_last]]).astype(np.float32) + + sigmas = torch.from_numpy(sigmas).to(dtype=torch.float32, device=device) + + # TODO: Support the full EDM scalings for all prediction types and timestep types + if self.config.timestep_type == "continuous" and self.config.prediction_type == "v_prediction": + self.timesteps = torch.Tensor([0.25 * sigma.log() for sigma in sigmas[:-1]]).to(device=device) + else: + self.timesteps = torch.from_numpy(timesteps.astype(np.float32)).to(device=device) + + self._step_index = None + self._begin_index = None + self.sigmas = sigmas.to("cpu") # to avoid too much CPU/GPU communication + + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + # Copied from https://github.com/crowsonkb/k-diffusion/blob/686dbad0f39640ea25c8a8c6a6e56bb40eacefa2/k_diffusion/sampling.py#L17 + def _convert_to_karras(self, in_sigmas: torch.Tensor, num_inference_steps) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from https://github.com/crowsonkb/k-diffusion/blob/686dbad0f39640ea25c8a8c6a6e56bb40eacefa2/k_diffusion/sampling.py#L26 + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.Tensor, + timestep: Union[float, torch.Tensor], + sample: torch.Tensor, + s_churn: float = 0.0, + s_tmin: float = 0.0, + s_tmax: float = float("inf"), + s_noise: float = 1.0, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[EulerDiscreteSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + s_churn (`float`): + s_tmin (`float`): + s_tmax (`float`): + s_noise (`float`, defaults to 1.0): + Scaling factor for noise added to the sample. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_euler_discrete.EulerDiscreteSchedulerOutput`] or + tuple. + + Returns: + [`~schedulers.scheduling_euler_discrete.EulerDiscreteSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_euler_discrete.EulerDiscreteSchedulerOutput`] is + returned, otherwise a tuple is returned where the first element is the sample tensor. + """ + + if isinstance(timestep, (int, torch.IntTensor, torch.LongTensor)): + raise ValueError( + ( + "Passing integer indices (e.g. from `enumerate(timesteps)`) as timesteps to" + " `EulerDiscreteScheduler.step()` is not supported. Make sure to pass" + " one of the `scheduler.timesteps` as a timestep." + ), + ) + + if not self.is_scale_input_called: + logger.warning( + "The `scale_model_input` function should be called before `step` to ensure correct denoising. " + "See `StableDiffusionPipeline` for a usage example." + ) + + if self.step_index is None: + self._init_step_index(timestep) + + # Upcast to avoid precision issues when computing prev_sample + sample = sample.to(torch.float32) + + sigma = self.sigmas[self.step_index] + + gamma = min(s_churn / (len(self.sigmas) - 1), 2**0.5 - 1) if s_tmin <= sigma <= s_tmax else 0.0 + + sigma_hat = sigma * (gamma + 1) + + if gamma > 0: + noise = randn_tensor( + model_output.shape, dtype=model_output.dtype, device=model_output.device, generator=generator + ) + eps = noise * s_noise + sample = sample + eps * (sigma_hat**2 - sigma**2) ** 0.5 + + # 1. compute predicted original sample (x_0) from sigma-scaled predicted noise + # NOTE: "original_sample" should not be an expected prediction_type but is left in for + # backwards compatibility + if self.config.prediction_type == "original_sample" or self.config.prediction_type == "sample": + pred_original_sample = model_output + elif self.config.prediction_type == "epsilon": + pred_original_sample = sample - sigma_hat * model_output + elif self.config.prediction_type == "v_prediction": + # denoised = model_output * c_out + input * c_skip + pred_original_sample = model_output * (-sigma / (sigma**2 + 1) ** 0.5) + (sample / (sigma**2 + 1)) + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, or `v_prediction`" + ) + + # 2. Convert to an ODE derivative + derivative = (sample - pred_original_sample) / sigma_hat + + dt = self.sigmas[self.step_index + 1] - sigma_hat + + prev_sample = sample + derivative * dt + + # Cast sample back to model compatible dtype + prev_sample = prev_sample.to(model_output.dtype) + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return ( + prev_sample, + pred_original_sample, + ) + + return EulerDiscreteSchedulerOutput(prev_sample=prev_sample, pred_original_sample=pred_original_sample) + + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.Tensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # self.begin_index is None when scheduler is used for training, or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + noisy_samples = original_samples + noise * sigma + return noisy_samples + + def get_velocity(self, sample: torch.Tensor, noise: torch.Tensor, timesteps: torch.Tensor) -> torch.Tensor: + if ( + isinstance(timesteps, int) + or isinstance(timesteps, torch.IntTensor) + or isinstance(timesteps, torch.LongTensor) + ): + raise ValueError( + ( + "Passing integer indices (e.g. from `enumerate(timesteps)`) as timesteps to" + " `EulerDiscreteScheduler.get_velocity()` is not supported. Make sure to pass" + " one of the `scheduler.timesteps` as a timestep." + ), + ) + + if sample.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(sample.device, dtype=torch.float32) + timesteps = timesteps.to(sample.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(sample.device) + timesteps = timesteps.to(sample.device) + + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + alphas_cumprod = self.alphas_cumprod.to(sample) + sqrt_alpha_prod = alphas_cumprod[step_indices] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(sample.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[step_indices]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(sample.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + velocity = sqrt_alpha_prod * noise - sqrt_one_minus_alpha_prod * sample + return velocity + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_euler_discrete_flax.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_euler_discrete_flax.py new file mode 100644 index 0000000000000000000000000000000000000000..b2b7d6e8c39602d8f387a1e4dcbf6320a2f9c26c --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_euler_discrete_flax.py @@ -0,0 +1,265 @@ +# Copyright 2024 Katherine Crowson and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import flax +import jax.numpy as jnp + +from ..configuration_utils import ConfigMixin, register_to_config +from .scheduling_utils_flax import ( + CommonSchedulerState, + FlaxKarrasDiffusionSchedulers, + FlaxSchedulerMixin, + FlaxSchedulerOutput, + broadcast_to_shape_from_left, +) + + +@flax.struct.dataclass +class EulerDiscreteSchedulerState: + common: CommonSchedulerState + + # setable values + init_noise_sigma: jnp.ndarray + timesteps: jnp.ndarray + sigmas: jnp.ndarray + num_inference_steps: Optional[int] = None + + @classmethod + def create( + cls, common: CommonSchedulerState, init_noise_sigma: jnp.ndarray, timesteps: jnp.ndarray, sigmas: jnp.ndarray + ): + return cls(common=common, init_noise_sigma=init_noise_sigma, timesteps=timesteps, sigmas=sigmas) + + +@dataclass +class FlaxEulerDiscreteSchedulerOutput(FlaxSchedulerOutput): + state: EulerDiscreteSchedulerState + + +class FlaxEulerDiscreteScheduler(FlaxSchedulerMixin, ConfigMixin): + """ + Euler scheduler (Algorithm 2) from Karras et al. (2022) https://huggingface.co/papers/2206.00364. . Based on the + original k-diffusion implementation by Katherine Crowson: + https://github.com/crowsonkb/k-diffusion/blob/481677d114f6ea445aa009cf5bd7a9cdee909e47/k_diffusion/sampling.py#L51 + + + [`~ConfigMixin`] takes care of storing all config attributes that are passed in the scheduler's `__init__` + function, such as `num_train_timesteps`. They can be accessed via `scheduler.config.num_train_timesteps`. + [`SchedulerMixin`] provides general loading and saving functionality via the [`SchedulerMixin.save_pretrained`] and + [`~SchedulerMixin.from_pretrained`] functions. + + Args: + num_train_timesteps (`int`): number of diffusion steps used to train the model. + beta_start (`float`): the starting `beta` value of inference. + beta_end (`float`): the final `beta` value. + beta_schedule (`str`): + the beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear` or `scaled_linear`. + trained_betas (`jnp.ndarray`, optional): + option to pass an array of betas directly to the constructor to bypass `beta_start`, `beta_end` etc. + prediction_type (`str`, default `epsilon`, optional): + prediction type of the scheduler function, one of `epsilon` (predicting the noise of the diffusion + process), `sample` (directly predicting the noisy sample`) or `v_prediction` (see section 2.4 + https://imagen.research.google/video/paper.pdf) + dtype (`jnp.dtype`, *optional*, defaults to `jnp.float32`): + the `dtype` used for params and computation. + """ + + _compatibles = [e.name for e in FlaxKarrasDiffusionSchedulers] + + dtype: jnp.dtype + + @property + def has_state(self): + return True + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[jnp.ndarray] = None, + prediction_type: str = "epsilon", + timestep_spacing: str = "linspace", + dtype: jnp.dtype = jnp.float32, + ): + self.dtype = dtype + + def create_state(self, common: Optional[CommonSchedulerState] = None) -> EulerDiscreteSchedulerState: + if common is None: + common = CommonSchedulerState.create(self) + + timesteps = jnp.arange(0, self.config.num_train_timesteps).round()[::-1] + sigmas = ((1 - common.alphas_cumprod) / common.alphas_cumprod) ** 0.5 + sigmas = jnp.interp(timesteps, jnp.arange(0, len(sigmas)), sigmas) + sigmas = jnp.concatenate([sigmas, jnp.array([0.0], dtype=self.dtype)]) + + # standard deviation of the initial noise distribution + if self.config.timestep_spacing in ["linspace", "trailing"]: + init_noise_sigma = sigmas.max() + else: + init_noise_sigma = (sigmas.max() ** 2 + 1) ** 0.5 + + return EulerDiscreteSchedulerState.create( + common=common, + init_noise_sigma=init_noise_sigma, + timesteps=timesteps, + sigmas=sigmas, + ) + + def scale_model_input(self, state: EulerDiscreteSchedulerState, sample: jnp.ndarray, timestep: int) -> jnp.ndarray: + """ + Scales the denoising model input by `(sigma**2 + 1) ** 0.5` to match the Euler algorithm. + + Args: + state (`EulerDiscreteSchedulerState`): + the `FlaxEulerDiscreteScheduler` state data class instance. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + timestep (`int`): + current discrete timestep in the diffusion chain. + + Returns: + `jnp.ndarray`: scaled input sample + """ + (step_index,) = jnp.where(state.timesteps == timestep, size=1) + step_index = step_index[0] + + sigma = state.sigmas[step_index] + sample = sample / ((sigma**2 + 1) ** 0.5) + return sample + + def set_timesteps( + self, state: EulerDiscreteSchedulerState, num_inference_steps: int, shape: Tuple = () + ) -> EulerDiscreteSchedulerState: + """ + Sets the timesteps used for the diffusion chain. Supporting function to be run before inference. + + Args: + state (`EulerDiscreteSchedulerState`): + the `FlaxEulerDiscreteScheduler` state data class instance. + num_inference_steps (`int`): + the number of diffusion steps used when generating samples with a pre-trained model. + """ + + if self.config.timestep_spacing == "linspace": + timesteps = jnp.linspace(self.config.num_train_timesteps - 1, 0, num_inference_steps, dtype=self.dtype) + elif self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // num_inference_steps + timesteps = (jnp.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(float) + timesteps += 1 + else: + raise ValueError( + f"timestep_spacing must be one of ['linspace', 'leading'], got {self.config.timestep_spacing}" + ) + + sigmas = ((1 - state.common.alphas_cumprod) / state.common.alphas_cumprod) ** 0.5 + sigmas = jnp.interp(timesteps, jnp.arange(0, len(sigmas)), sigmas) + sigmas = jnp.concatenate([sigmas, jnp.array([0.0], dtype=self.dtype)]) + + # standard deviation of the initial noise distribution + if self.config.timestep_spacing in ["linspace", "trailing"]: + init_noise_sigma = sigmas.max() + else: + init_noise_sigma = (sigmas.max() ** 2 + 1) ** 0.5 + + return state.replace( + timesteps=timesteps, + sigmas=sigmas, + num_inference_steps=num_inference_steps, + init_noise_sigma=init_noise_sigma, + ) + + def step( + self, + state: EulerDiscreteSchedulerState, + model_output: jnp.ndarray, + timestep: int, + sample: jnp.ndarray, + return_dict: bool = True, + ) -> Union[FlaxEulerDiscreteSchedulerOutput, Tuple]: + """ + Predict the sample at the previous timestep by reversing the SDE. Core function to propagate the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + state (`EulerDiscreteSchedulerState`): + the `FlaxEulerDiscreteScheduler` state data class instance. + model_output (`jnp.ndarray`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + order: coefficient for multi-step inference. + return_dict (`bool`): option for returning tuple rather than FlaxEulerDiscreteScheduler class + + Returns: + [`FlaxEulerDiscreteScheduler`] or `tuple`: [`FlaxEulerDiscreteScheduler`] if `return_dict` is True, + otherwise a `tuple`. When returning a tuple, the first element is the sample tensor. + + """ + if state.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + (step_index,) = jnp.where(state.timesteps == timestep, size=1) + step_index = step_index[0] + + sigma = state.sigmas[step_index] + + # 1. compute predicted original sample (x_0) from sigma-scaled predicted noise + if self.config.prediction_type == "epsilon": + pred_original_sample = sample - sigma * model_output + elif self.config.prediction_type == "v_prediction": + # * c_out + input * c_skip + pred_original_sample = model_output * (-sigma / (sigma**2 + 1) ** 0.5) + (sample / (sigma**2 + 1)) + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, or `v_prediction`" + ) + + # 2. Convert to an ODE derivative + derivative = (sample - pred_original_sample) / sigma + + # dt = sigma_down - sigma + dt = state.sigmas[step_index + 1] - sigma + + prev_sample = sample + derivative * dt + + if not return_dict: + return (prev_sample, state) + + return FlaxEulerDiscreteSchedulerOutput(prev_sample=prev_sample, state=state) + + def add_noise( + self, + state: EulerDiscreteSchedulerState, + original_samples: jnp.ndarray, + noise: jnp.ndarray, + timesteps: jnp.ndarray, + ) -> jnp.ndarray: + sigma = state.sigmas[timesteps].flatten() + sigma = broadcast_to_shape_from_left(sigma, noise.shape) + + noisy_samples = original_samples + noise * sigma + + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_flow_match_euler_discrete.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_flow_match_euler_discrete.py new file mode 100644 index 0000000000000000000000000000000000000000..575423ee80e7e863f47c02231954e03ed947dc67 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_flow_match_euler_discrete.py @@ -0,0 +1,561 @@ +# Copyright 2024 Stability AI, Katherine Crowson and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput, is_scipy_available, logging +from .scheduling_utils import SchedulerMixin + + +if is_scipy_available(): + import scipy.stats + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + + +@dataclass +class FlowMatchEulerDiscreteSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + """ + + prev_sample: torch.FloatTensor + + +class FlowMatchEulerDiscreteScheduler(SchedulerMixin, ConfigMixin): + """ + Euler scheduler. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + shift (`float`, defaults to 1.0): + The shift value for the timestep schedule. + use_dynamic_shifting (`bool`, defaults to False): + Whether to apply timestep shifting on-the-fly based on the image resolution. + base_shift (`float`, defaults to 0.5): + Value to stabilize image generation. Increasing `base_shift` reduces variation and image is more consistent + with desired output. + max_shift (`float`, defaults to 1.15): + Value change allowed to latent vectors. Increasing `max_shift` encourages more variation and image may be + more exaggerated or stylized. + base_image_seq_len (`int`, defaults to 256): + The base image sequence length. + max_image_seq_len (`int`, defaults to 4096): + The maximum image sequence length. + invert_sigmas (`bool`, defaults to False): + Whether to invert the sigmas. + shift_terminal (`float`, defaults to None): + The end value of the shifted timestep schedule. + use_karras_sigmas (`bool`, defaults to False): + Whether to use Karras sigmas for step sizes in the noise schedule during sampling. + use_exponential_sigmas (`bool`, defaults to False): + Whether to use exponential sigmas for step sizes in the noise schedule during sampling. + use_beta_sigmas (`bool`, defaults to False): + Whether to use beta sigmas for step sizes in the noise schedule during sampling. + time_shift_type (`str`, defaults to "exponential"): + The type of dynamic resolution-dependent timestep shifting to apply. Either "exponential" or "linear". + stochastic_sampling (`bool`, defaults to False): + Whether to use stochastic sampling. + """ + + _compatibles = [] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + shift: float = 1.0, + use_dynamic_shifting: bool = False, + base_shift: Optional[float] = 0.5, + max_shift: Optional[float] = 1.15, + base_image_seq_len: Optional[int] = 256, + max_image_seq_len: Optional[int] = 4096, + invert_sigmas: bool = False, + shift_terminal: Optional[float] = None, + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + time_shift_type: str = "exponential", + stochastic_sampling: bool = False, + ): + if self.config.use_beta_sigmas and not is_scipy_available(): + raise ImportError("Make sure to install scipy if you want to use beta sigmas.") + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if time_shift_type not in {"exponential", "linear"}: + raise ValueError("`time_shift_type` must either be 'exponential' or 'linear'.") + + timesteps = np.linspace(1, num_train_timesteps, num_train_timesteps, dtype=np.float32)[::-1].copy() + timesteps = torch.from_numpy(timesteps).to(dtype=torch.float32) + + sigmas = timesteps / num_train_timesteps + if not use_dynamic_shifting: + # when use_dynamic_shifting is True, we apply the timestep shifting on the fly based on the image resolution + sigmas = shift * sigmas / (1 + (shift - 1) * sigmas) + + self.timesteps = sigmas * num_train_timesteps + + self._step_index = None + self._begin_index = None + + self._shift = shift + + self.sigmas = sigmas.to("cpu") # to avoid too much CPU/GPU communication + self.sigma_min = self.sigmas[-1].item() + self.sigma_max = self.sigmas[0].item() + + @property + def shift(self): + """ + The value used for shifting. + """ + return self._shift + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def set_shift(self, shift: float): + self._shift = shift + + def scale_noise( + self, + sample: torch.FloatTensor, + timestep: Union[float, torch.FloatTensor], + noise: Optional[torch.FloatTensor] = None, + ) -> torch.FloatTensor: + """ + Forward process in flow-matching + + Args: + sample (`torch.FloatTensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.FloatTensor`: + A scaled input sample. + """ + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=sample.device, dtype=sample.dtype) + + if sample.device.type == "mps" and torch.is_floating_point(timestep): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(sample.device, dtype=torch.float32) + timestep = timestep.to(sample.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(sample.device) + timestep = timestep.to(sample.device) + + # self.begin_index is None when scheduler is used for training, or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timestep] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timestep.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timestep.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(sample.shape): + sigma = sigma.unsqueeze(-1) + + sample = sigma * noise + (1.0 - sigma) * sample + + return sample + + def _sigma_to_t(self, sigma): + return sigma * self.config.num_train_timesteps + + def time_shift(self, mu: float, sigma: float, t: torch.Tensor): + if self.config.time_shift_type == "exponential": + return self._time_shift_exponential(mu, sigma, t) + elif self.config.time_shift_type == "linear": + return self._time_shift_linear(mu, sigma, t) + + def stretch_shift_to_terminal(self, t: torch.Tensor) -> torch.Tensor: + r""" + Stretches and shifts the timestep schedule to ensure it terminates at the configured `shift_terminal` config + value. + + Reference: + https://github.com/Lightricks/LTX-Video/blob/a01a171f8fe3d99dce2728d60a73fecf4d4238ae/ltx_video/schedulers/rf.py#L51 + + Args: + t (`torch.Tensor`): + A tensor of timesteps to be stretched and shifted. + + Returns: + `torch.Tensor`: + A tensor of adjusted timesteps such that the final value equals `self.config.shift_terminal`. + """ + one_minus_z = 1 - t + scale_factor = one_minus_z[-1] / (1 - self.config.shift_terminal) + stretched_t = 1 - (one_minus_z / scale_factor) + return stretched_t + + def set_timesteps( + self, + num_inference_steps: Optional[int] = None, + device: Union[str, torch.device] = None, + sigmas: Optional[List[float]] = None, + mu: Optional[float] = None, + timesteps: Optional[List[float]] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`, *optional*): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + sigmas (`List[float]`, *optional*): + Custom values for sigmas to be used for each diffusion step. If `None`, the sigmas are computed + automatically. + mu (`float`, *optional*): + Determines the amount of shifting applied to sigmas when performing resolution-dependent timestep + shifting. + timesteps (`List[float]`, *optional*): + Custom values for timesteps to be used for each diffusion step. If `None`, the timesteps are computed + automatically. + """ + if self.config.use_dynamic_shifting and mu is None: + raise ValueError("`mu` must be passed when `use_dynamic_shifting` is set to be `True`") + + if sigmas is not None and timesteps is not None: + if len(sigmas) != len(timesteps): + raise ValueError("`sigmas` and `timesteps` should have the same length") + + if num_inference_steps is not None: + if (sigmas is not None and len(sigmas) != num_inference_steps) or ( + timesteps is not None and len(timesteps) != num_inference_steps + ): + raise ValueError( + "`sigmas` and `timesteps` should have the same length as num_inference_steps, if `num_inference_steps` is provided" + ) + else: + num_inference_steps = len(sigmas) if sigmas is not None else len(timesteps) + + self.num_inference_steps = num_inference_steps + + # 1. Prepare default sigmas + is_timesteps_provided = timesteps is not None + + if is_timesteps_provided: + timesteps = np.array(timesteps).astype(np.float32) + + if sigmas is None: + if timesteps is None: + timesteps = np.linspace( + self._sigma_to_t(self.sigma_max), self._sigma_to_t(self.sigma_min), num_inference_steps + ) + sigmas = timesteps / self.config.num_train_timesteps + else: + sigmas = np.array(sigmas).astype(np.float32) + num_inference_steps = len(sigmas) + + # 2. Perform timestep shifting. Either no shifting is applied, or resolution-dependent shifting of + # "exponential" or "linear" type is applied + if self.config.use_dynamic_shifting: + sigmas = self.time_shift(mu, 1.0, sigmas) + else: + sigmas = self.shift * sigmas / (1 + (self.shift - 1) * sigmas) + + # 3. If required, stretch the sigmas schedule to terminate at the configured `shift_terminal` value + if self.config.shift_terminal: + sigmas = self.stretch_shift_to_terminal(sigmas) + + # 4. If required, convert sigmas to one of karras, exponential, or beta sigma schedules + if self.config.use_karras_sigmas: + sigmas = self._convert_to_karras(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + elif self.config.use_exponential_sigmas: + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + elif self.config.use_beta_sigmas: + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + + # 5. Convert sigmas and timesteps to tensors and move to specified device + sigmas = torch.from_numpy(sigmas).to(dtype=torch.float32, device=device) + if not is_timesteps_provided: + timesteps = sigmas * self.config.num_train_timesteps + else: + timesteps = torch.from_numpy(timesteps).to(dtype=torch.float32, device=device) + + # 6. Append the terminal sigma value. + # If a model requires inverted sigma schedule for denoising but timesteps without inversion, the + # `invert_sigmas` flag can be set to `True`. This case is only required in Mochi + if self.config.invert_sigmas: + sigmas = 1.0 - sigmas + timesteps = sigmas * self.config.num_train_timesteps + sigmas = torch.cat([sigmas, torch.ones(1, device=sigmas.device)]) + else: + sigmas = torch.cat([sigmas, torch.zeros(1, device=sigmas.device)]) + + self.timesteps = timesteps + self.sigmas = sigmas + self._step_index = None + self._begin_index = None + + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.FloatTensor, + timestep: Union[float, torch.FloatTensor], + sample: torch.FloatTensor, + s_churn: float = 0.0, + s_tmin: float = 0.0, + s_tmax: float = float("inf"), + s_noise: float = 1.0, + generator: Optional[torch.Generator] = None, + per_token_timesteps: Optional[torch.Tensor] = None, + return_dict: bool = True, + ) -> Union[FlowMatchEulerDiscreteSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.FloatTensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.FloatTensor`): + A current instance of a sample created by the diffusion process. + s_churn (`float`): + s_tmin (`float`): + s_tmax (`float`): + s_noise (`float`, defaults to 1.0): + Scaling factor for noise added to the sample. + generator (`torch.Generator`, *optional*): + A random number generator. + per_token_timesteps (`torch.Tensor`, *optional*): + The timesteps for each token in the sample. + return_dict (`bool`): + Whether or not to return a + [`~schedulers.scheduling_flow_match_euler_discrete.FlowMatchEulerDiscreteSchedulerOutput`] or tuple. + + Returns: + [`~schedulers.scheduling_flow_match_euler_discrete.FlowMatchEulerDiscreteSchedulerOutput`] or `tuple`: + If return_dict is `True`, + [`~schedulers.scheduling_flow_match_euler_discrete.FlowMatchEulerDiscreteSchedulerOutput`] is returned, + otherwise a tuple is returned where the first element is the sample tensor. + """ + + if ( + isinstance(timestep, int) + or isinstance(timestep, torch.IntTensor) + or isinstance(timestep, torch.LongTensor) + ): + raise ValueError( + ( + "Passing integer indices (e.g. from `enumerate(timesteps)`) as timesteps to" + " `FlowMatchEulerDiscreteScheduler.step()` is not supported. Make sure to pass" + " one of the `scheduler.timesteps` as a timestep." + ), + ) + + if self.step_index is None: + self._init_step_index(timestep) + + # Upcast to avoid precision issues when computing prev_sample + sample = sample.to(torch.float32) + + if per_token_timesteps is not None: + per_token_sigmas = per_token_timesteps / self.config.num_train_timesteps + + sigmas = self.sigmas[:, None, None] + lower_mask = sigmas < per_token_sigmas[None] - 1e-6 + lower_sigmas = lower_mask * sigmas + lower_sigmas, _ = lower_sigmas.max(dim=0) + + current_sigma = per_token_sigmas[..., None] + next_sigma = lower_sigmas[..., None] + dt = current_sigma - next_sigma + else: + sigma_idx = self.step_index + sigma = self.sigmas[sigma_idx] + sigma_next = self.sigmas[sigma_idx + 1] + + current_sigma = sigma + next_sigma = sigma_next + dt = sigma_next - sigma + + if self.config.stochastic_sampling: + x0 = sample - current_sigma * model_output + noise = torch.randn_like(sample) + prev_sample = (1.0 - next_sigma) * x0 + next_sigma * noise + else: + prev_sample = sample + dt * model_output + + # upon completion increase step index by one + self._step_index += 1 + if per_token_timesteps is None: + # Cast sample back to model compatible dtype + prev_sample = prev_sample.to(model_output.dtype) + + if not return_dict: + return (prev_sample,) + + return FlowMatchEulerDiscreteSchedulerOutput(prev_sample=prev_sample) + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_karras + def _convert_to_karras(self, in_sigmas: torch.Tensor, num_inference_steps) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_exponential + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_beta + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + def _time_shift_exponential(self, mu, sigma, t): + return math.exp(mu) / (math.exp(mu) + (1 / t - 1) ** sigma) + + def _time_shift_linear(self, mu, sigma, t): + return mu / (mu + (1 / t - 1) ** sigma) + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_flow_match_heun_discrete.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_flow_match_heun_discrete.py new file mode 100644 index 0000000000000000000000000000000000000000..2addc5f3eeec05019a01169ca0666eb7a516a924 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_flow_match_heun_discrete.py @@ -0,0 +1,321 @@ +# Copyright 2024 Stability AI, Katherine Crowson and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput, logging +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import SchedulerMixin + + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + + +@dataclass +class FlowMatchHeunDiscreteSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + """ + + prev_sample: torch.FloatTensor + + +class FlowMatchHeunDiscreteScheduler(SchedulerMixin, ConfigMixin): + """ + Heun scheduler. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + shift (`float`, defaults to 1.0): + The shift value for the timestep schedule. + """ + + _compatibles = [] + order = 2 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + shift: float = 1.0, + ): + timesteps = np.linspace(1, num_train_timesteps, num_train_timesteps, dtype=np.float32)[::-1].copy() + timesteps = torch.from_numpy(timesteps).to(dtype=torch.float32) + + sigmas = timesteps / num_train_timesteps + sigmas = shift * sigmas / (1 + (shift - 1) * sigmas) + + self.timesteps = sigmas * num_train_timesteps + + self._step_index = None + self._begin_index = None + + self.sigmas = sigmas.to("cpu") # to avoid too much CPU/GPU communication + self.sigma_min = self.sigmas[-1].item() + self.sigma_max = self.sigmas[0].item() + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def scale_noise( + self, + sample: torch.FloatTensor, + timestep: Union[float, torch.FloatTensor], + noise: Optional[torch.FloatTensor] = None, + ) -> torch.FloatTensor: + """ + Forward process in flow-matching + + Args: + sample (`torch.FloatTensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.FloatTensor`: + A scaled input sample. + """ + if self.step_index is None: + self._init_step_index(timestep) + + sigma = self.sigmas[self.step_index] + sample = sigma * noise + (1.0 - sigma) * sample + + return sample + + def _sigma_to_t(self, sigma): + return sigma * self.config.num_train_timesteps + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + self.num_inference_steps = num_inference_steps + + timesteps = np.linspace( + self._sigma_to_t(self.sigma_max), self._sigma_to_t(self.sigma_min), num_inference_steps + ) + + sigmas = timesteps / self.config.num_train_timesteps + sigmas = self.config.shift * sigmas / (1 + (self.config.shift - 1) * sigmas) + sigmas = torch.from_numpy(sigmas).to(dtype=torch.float32, device=device) + + timesteps = sigmas * self.config.num_train_timesteps + timesteps = torch.cat([timesteps[:1], timesteps[1:].repeat_interleave(2)]) + self.timesteps = timesteps.to(device=device) + + sigmas = torch.cat([sigmas, torch.zeros(1, device=sigmas.device)]) + self.sigmas = torch.cat([sigmas[:1], sigmas[1:-1].repeat_interleave(2), sigmas[-1:]]) + + # empty dt and derivative + self.prev_derivative = None + self.dt = None + + self._step_index = None + self._begin_index = None + + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + @property + def state_in_first_order(self): + return self.dt is None + + def step( + self, + model_output: torch.FloatTensor, + timestep: Union[float, torch.FloatTensor], + sample: torch.FloatTensor, + s_churn: float = 0.0, + s_tmin: float = 0.0, + s_tmax: float = float("inf"), + s_noise: float = 1.0, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[FlowMatchHeunDiscreteSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.FloatTensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.FloatTensor`): + A current instance of a sample created by the diffusion process. + s_churn (`float`): + s_tmin (`float`): + s_tmax (`float`): + s_noise (`float`, defaults to 1.0): + Scaling factor for noise added to the sample. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`): + Whether or not to return a + [`~schedulers.scheduling_flow_match_heun_discrete.FlowMatchHeunDiscreteSchedulerOutput`] tuple. + + Returns: + [`~schedulers.scheduling_flow_match_heun_discrete.FlowMatchHeunDiscreteSchedulerOutput`] or `tuple`: + If return_dict is `True`, + [`~schedulers.scheduling_flow_match_heun_discrete.FlowMatchHeunDiscreteSchedulerOutput`] is returned, + otherwise a tuple is returned where the first element is the sample tensor. + """ + + if ( + isinstance(timestep, int) + or isinstance(timestep, torch.IntTensor) + or isinstance(timestep, torch.LongTensor) + ): + raise ValueError( + ( + "Passing integer indices (e.g. from `enumerate(timesteps)`) as timesteps to" + " `FlowMatchHeunDiscreteScheduler.step()` is not supported. Make sure to pass" + " one of the `scheduler.timesteps` as a timestep." + ), + ) + + if self.step_index is None: + self._init_step_index(timestep) + + # Upcast to avoid precision issues when computing prev_sample + sample = sample.to(torch.float32) + + if self.state_in_first_order: + sigma = self.sigmas[self.step_index] + sigma_next = self.sigmas[self.step_index + 1] + else: + # 2nd order / Heun's method + sigma = self.sigmas[self.step_index - 1] + sigma_next = self.sigmas[self.step_index] + + gamma = min(s_churn / (len(self.sigmas) - 1), 2**0.5 - 1) if s_tmin <= sigma <= s_tmax else 0.0 + + sigma_hat = sigma * (gamma + 1) + + if gamma > 0: + noise = randn_tensor( + model_output.shape, dtype=model_output.dtype, device=model_output.device, generator=generator + ) + eps = noise * s_noise + sample = sample + eps * (sigma_hat**2 - sigma**2) ** 0.5 + + if self.state_in_first_order: + # 1. compute predicted original sample (x_0) from sigma-scaled predicted noise + denoised = sample - model_output * sigma + # 2. convert to an ODE derivative for 1st order + derivative = (sample - denoised) / sigma_hat + # 3. Delta timestep + dt = sigma_next - sigma_hat + + # store for 2nd order step + self.prev_derivative = derivative + self.dt = dt + self.sample = sample + else: + # 1. compute predicted original sample (x_0) from sigma-scaled predicted noise + denoised = sample - model_output * sigma_next + # 2. 2nd order / Heun's method + derivative = (sample - denoised) / sigma_next + derivative = 0.5 * (self.prev_derivative + derivative) + + # 3. take prev timestep & sample + dt = self.dt + sample = self.sample + + # free dt and derivative + # Note, this puts the scheduler in "first order mode" + self.prev_derivative = None + self.dt = None + self.sample = None + + prev_sample = sample + derivative * dt + # Cast sample back to model compatible dtype + prev_sample = prev_sample.to(model_output.dtype) + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return (prev_sample,) + + return FlowMatchHeunDiscreteSchedulerOutput(prev_sample=prev_sample) + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_flow_match_lcm.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_flow_match_lcm.py new file mode 100644 index 0000000000000000000000000000000000000000..d79556ae8077b664131d5997aa4ae238909723d5 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_flow_match_lcm.py @@ -0,0 +1,561 @@ +# Copyright 2024 Stability AI, Katherine Crowson and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput, is_scipy_available, logging +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import SchedulerMixin + + +if is_scipy_available(): + import scipy.stats + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + + +@dataclass +class FlowMatchLCMSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.FloatTensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + """ + + prev_sample: torch.FloatTensor + + +class FlowMatchLCMScheduler(SchedulerMixin, ConfigMixin): + """ + LCM scheduler for Flow Matching. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + shift (`float`, defaults to 1.0): + The shift value for the timestep schedule. + use_dynamic_shifting (`bool`, defaults to False): + Whether to apply timestep shifting on-the-fly based on the image resolution. + base_shift (`float`, defaults to 0.5): + Value to stabilize image generation. Increasing `base_shift` reduces variation and image is more consistent + with desired output. + max_shift (`float`, defaults to 1.15): + Value change allowed to latent vectors. Increasing `max_shift` encourages more variation and image may be + more exaggerated or stylized. + base_image_seq_len (`int`, defaults to 256): + The base image sequence length. + max_image_seq_len (`int`, defaults to 4096): + The maximum image sequence length. + invert_sigmas (`bool`, defaults to False): + Whether to invert the sigmas. + shift_terminal (`float`, defaults to None): + The end value of the shifted timestep schedule. + use_karras_sigmas (`bool`, defaults to False): + Whether to use Karras sigmas for step sizes in the noise schedule during sampling. + use_exponential_sigmas (`bool`, defaults to False): + Whether to use exponential sigmas for step sizes in the noise schedule during sampling. + use_beta_sigmas (`bool`, defaults to False): + Whether to use beta sigmas for step sizes in the noise schedule during sampling. + time_shift_type (`str`, defaults to "exponential"): + The type of dynamic resolution-dependent timestep shifting to apply. Either "exponential" or "linear". + scale_factors ('list', defaults to None) + It defines how to scale the latents at which predictions are made. + upscale_mode ('str', defaults to 'bicubic') + Upscaling method, applied if scale-wise generation is considered + """ + + _compatibles = [] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + shift: float = 1.0, + use_dynamic_shifting: bool = False, + base_shift: Optional[float] = 0.5, + max_shift: Optional[float] = 1.15, + base_image_seq_len: Optional[int] = 256, + max_image_seq_len: Optional[int] = 4096, + invert_sigmas: bool = False, + shift_terminal: Optional[float] = None, + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + time_shift_type: str = "exponential", + scale_factors: Optional[List[float]] = None, + upscale_mode: Optional[str] = "bicubic", + ): + if self.config.use_beta_sigmas and not is_scipy_available(): + raise ImportError("Make sure to install scipy if you want to use beta sigmas.") + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if time_shift_type not in {"exponential", "linear"}: + raise ValueError("`time_shift_type` must either be 'exponential' or 'linear'.") + + timesteps = np.linspace(1, num_train_timesteps, num_train_timesteps, dtype=np.float32)[::-1].copy() + timesteps = torch.from_numpy(timesteps).to(dtype=torch.float32) + + sigmas = timesteps / num_train_timesteps + if not use_dynamic_shifting: + # when use_dynamic_shifting is True, we apply the timestep shifting on the fly based on the image resolution + sigmas = shift * sigmas / (1 + (shift - 1) * sigmas) + + self.timesteps = sigmas * num_train_timesteps + + self._step_index = None + self._begin_index = None + + self._shift = shift + + self._init_size = None + self._scale_factors = scale_factors + self._upscale_mode = upscale_mode + + self.sigmas = sigmas.to("cpu") # to avoid too much CPU/GPU communication + self.sigma_min = self.sigmas[-1].item() + self.sigma_max = self.sigmas[0].item() + + @property + def shift(self): + """ + The value used for shifting. + """ + return self._shift + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def set_shift(self, shift: float): + self._shift = shift + + def set_scale_factors(self, scale_factors: list, upscale_mode): + """ + Sets scale factors for a scale-wise generation regime. + + Args: + scale_factors (`list`): + The scale factors for each step + upscale_mode (`str`): + Upscaling method + """ + self._scale_factors = scale_factors + self._upscale_mode = upscale_mode + + def scale_noise( + self, + sample: torch.FloatTensor, + timestep: Union[float, torch.FloatTensor], + noise: Optional[torch.FloatTensor] = None, + ) -> torch.FloatTensor: + """ + Forward process in flow-matching + + Args: + sample (`torch.FloatTensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.FloatTensor`: + A scaled input sample. + """ + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=sample.device, dtype=sample.dtype) + + if sample.device.type == "mps" and torch.is_floating_point(timestep): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(sample.device, dtype=torch.float32) + timestep = timestep.to(sample.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(sample.device) + timestep = timestep.to(sample.device) + + # self.begin_index is None when scheduler is used for training, or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timestep] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timestep.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timestep.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(sample.shape): + sigma = sigma.unsqueeze(-1) + + sample = sigma * noise + (1.0 - sigma) * sample + + return sample + + def _sigma_to_t(self, sigma): + return sigma * self.config.num_train_timesteps + + def time_shift(self, mu: float, sigma: float, t: torch.Tensor): + if self.config.time_shift_type == "exponential": + return self._time_shift_exponential(mu, sigma, t) + elif self.config.time_shift_type == "linear": + return self._time_shift_linear(mu, sigma, t) + + def stretch_shift_to_terminal(self, t: torch.Tensor) -> torch.Tensor: + r""" + Stretches and shifts the timestep schedule to ensure it terminates at the configured `shift_terminal` config + value. + + Reference: + https://github.com/Lightricks/LTX-Video/blob/a01a171f8fe3d99dce2728d60a73fecf4d4238ae/ltx_video/schedulers/rf.py#L51 + + Args: + t (`torch.Tensor`): + A tensor of timesteps to be stretched and shifted. + + Returns: + `torch.Tensor`: + A tensor of adjusted timesteps such that the final value equals `self.config.shift_terminal`. + """ + one_minus_z = 1 - t + scale_factor = one_minus_z[-1] / (1 - self.config.shift_terminal) + stretched_t = 1 - (one_minus_z / scale_factor) + return stretched_t + + def set_timesteps( + self, + num_inference_steps: Optional[int] = None, + device: Union[str, torch.device] = None, + sigmas: Optional[List[float]] = None, + mu: Optional[float] = None, + timesteps: Optional[List[float]] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`, *optional*): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + sigmas (`List[float]`, *optional*): + Custom values for sigmas to be used for each diffusion step. If `None`, the sigmas are computed + automatically. + mu (`float`, *optional*): + Determines the amount of shifting applied to sigmas when performing resolution-dependent timestep + shifting. + timesteps (`List[float]`, *optional*): + Custom values for timesteps to be used for each diffusion step. If `None`, the timesteps are computed + automatically. + """ + if self.config.use_dynamic_shifting and mu is None: + raise ValueError("`mu` must be passed when `use_dynamic_shifting` is set to be `True`") + + if sigmas is not None and timesteps is not None: + if len(sigmas) != len(timesteps): + raise ValueError("`sigmas` and `timesteps` should have the same length") + + if num_inference_steps is not None: + if (sigmas is not None and len(sigmas) != num_inference_steps) or ( + timesteps is not None and len(timesteps) != num_inference_steps + ): + raise ValueError( + "`sigmas` and `timesteps` should have the same length as num_inference_steps, if `num_inference_steps` is provided" + ) + else: + num_inference_steps = len(sigmas) if sigmas is not None else len(timesteps) + + self.num_inference_steps = num_inference_steps + + # 1. Prepare default sigmas + is_timesteps_provided = timesteps is not None + + if is_timesteps_provided: + timesteps = np.array(timesteps).astype(np.float32) + + if sigmas is None: + if timesteps is None: + timesteps = np.linspace( + self._sigma_to_t(self.sigma_max), self._sigma_to_t(self.sigma_min), num_inference_steps + ) + sigmas = timesteps / self.config.num_train_timesteps + else: + sigmas = np.array(sigmas).astype(np.float32) + num_inference_steps = len(sigmas) + + # 2. Perform timestep shifting. Either no shifting is applied, or resolution-dependent shifting of + # "exponential" or "linear" type is applied + if self.config.use_dynamic_shifting: + sigmas = self.time_shift(mu, 1.0, sigmas) + else: + sigmas = self.shift * sigmas / (1 + (self.shift - 1) * sigmas) + + # 3. If required, stretch the sigmas schedule to terminate at the configured `shift_terminal` value + if self.config.shift_terminal: + sigmas = self.stretch_shift_to_terminal(sigmas) + + # 4. If required, convert sigmas to one of karras, exponential, or beta sigma schedules + if self.config.use_karras_sigmas: + sigmas = self._convert_to_karras(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + elif self.config.use_exponential_sigmas: + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + elif self.config.use_beta_sigmas: + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + + # 5. Convert sigmas and timesteps to tensors and move to specified device + sigmas = torch.from_numpy(sigmas).to(dtype=torch.float32, device=device) + if not is_timesteps_provided: + timesteps = sigmas * self.config.num_train_timesteps + else: + timesteps = torch.from_numpy(timesteps).to(dtype=torch.float32, device=device) + + # 6. Append the terminal sigma value. + # If a model requires inverted sigma schedule for denoising but timesteps without inversion, the + # `invert_sigmas` flag can be set to `True`. This case is only required in Mochi + if self.config.invert_sigmas: + sigmas = 1.0 - sigmas + timesteps = sigmas * self.config.num_train_timesteps + sigmas = torch.cat([sigmas, torch.ones(1, device=sigmas.device)]) + else: + sigmas = torch.cat([sigmas, torch.zeros(1, device=sigmas.device)]) + + self.timesteps = timesteps + self.sigmas = sigmas + self._step_index = None + self._begin_index = None + + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.FloatTensor, + timestep: Union[float, torch.FloatTensor], + sample: torch.FloatTensor, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[FlowMatchLCMSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.FloatTensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.FloatTensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_flow_match_lcm.FlowMatchLCMSchedulerOutput`] or + tuple. + + Returns: + [`~schedulers.scheduling_flow_match_lcm.FlowMatchLCMSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_flow_match_lcm.FlowMatchLCMSchedulerOutput`] is + returned, otherwise a tuple is returned where the first element is the sample tensor. + """ + + if ( + isinstance(timestep, int) + or isinstance(timestep, torch.IntTensor) + or isinstance(timestep, torch.LongTensor) + ): + raise ValueError( + ( + "Passing integer indices (e.g. from `enumerate(timesteps)`) as timesteps to" + " `FlowMatchLCMScheduler.step()` is not supported. Make sure to pass" + " one of the `scheduler.timesteps` as a timestep." + ), + ) + + if self._scale_factors and self._upscale_mode and len(self.timesteps) != len(self._scale_factors) + 1: + raise ValueError( + "`_scale_factors` should have the same length as `timesteps` - 1, if `_scale_factors` are set." + ) + + if self._init_size is None or self.step_index is None: + self._init_size = model_output.size()[2:] + + if self.step_index is None: + self._init_step_index(timestep) + + # Upcast to avoid precision issues when computing prev_sample + sample = sample.to(torch.float32) + + sigma = self.sigmas[self.step_index] + sigma_next = self.sigmas[self.step_index + 1] + x0_pred = sample - sigma * model_output + + if self._scale_factors and self._upscale_mode: + if self._step_index < len(self._scale_factors): + size = [round(self._scale_factors[self._step_index] * size) for size in self._init_size] + x0_pred = torch.nn.functional.interpolate(x0_pred, size=size, mode=self._upscale_mode) + + noise = randn_tensor(x0_pred.shape, generator=generator, device=x0_pred.device, dtype=x0_pred.dtype) + prev_sample = (1 - sigma_next) * x0_pred + sigma_next * noise + + # upon completion increase step index by one + self._step_index += 1 + # Cast sample back to model compatible dtype + prev_sample = prev_sample.to(model_output.dtype) + + if not return_dict: + return (prev_sample,) + + return FlowMatchLCMSchedulerOutput(prev_sample=prev_sample) + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_karras + def _convert_to_karras(self, in_sigmas: torch.Tensor, num_inference_steps) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_exponential + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_beta + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + def _time_shift_exponential(self, mu, sigma, t): + return math.exp(mu) / (math.exp(mu) + (1 / t - 1) ** sigma) + + def _time_shift_linear(self, mu, sigma, t): + return mu / (mu + (1 / t - 1) ** sigma) + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_heun_discrete.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_heun_discrete.py new file mode 100644 index 0000000000000000000000000000000000000000..26a2beab6ee5d9136d88ec48f9a74d9549926842 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_heun_discrete.py @@ -0,0 +1,610 @@ +# Copyright 2024 Katherine Crowson, The HuggingFace Team and hlky. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput, is_scipy_available +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin + + +if is_scipy_available(): + import scipy.stats + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->HeunDiscrete +class HeunDiscreteSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +class HeunDiscreteScheduler(SchedulerMixin, ConfigMixin): + """ + Scheduler with Heun steps for discrete beta schedules. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear` or `scaled_linear`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + clip_sample (`bool`, defaults to `True`): + Clip the predicted sample for numerical stability. + clip_sample_range (`float`, defaults to 1.0): + The maximum magnitude for sample clipping. Valid only when `clip_sample=True`. + use_karras_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use Karras sigmas for step sizes in the noise schedule during the sampling process. If `True`, + the sigmas are determined according to a sequence of noise levels {σi}. + use_exponential_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use exponential sigmas for step sizes in the noise schedule during the sampling process. + use_beta_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use beta sigmas for step sizes in the noise schedule during the sampling process. Refer to [Beta + Sampling is All You Need](https://huggingface.co/papers/2407.12173) for more information. + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 2 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.00085, # sensible defaults + beta_end: float = 0.012, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + prediction_type: str = "epsilon", + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + clip_sample: Optional[bool] = False, + clip_sample_range: float = 1.0, + timestep_spacing: str = "linspace", + steps_offset: int = 0, + ): + if self.config.use_beta_sigmas and not is_scipy_available(): + raise ImportError("Make sure to install scipy if you want to use beta sigmas.") + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps, alpha_transform_type="cosine") + elif beta_schedule == "exp": + self.betas = betas_for_alpha_bar(num_train_timesteps, alpha_transform_type="exp") + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + # set all values + self.set_timesteps(num_train_timesteps, None, num_train_timesteps) + self.use_karras_sigmas = use_karras_sigmas + + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + @property + def init_noise_sigma(self): + # standard deviation of the initial noise distribution + if self.config.timestep_spacing in ["linspace", "trailing"]: + return self.sigmas.max() + + return (self.sigmas.max() ** 2 + 1) ** 0.5 + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def scale_model_input( + self, + sample: torch.Tensor, + timestep: Union[float, torch.Tensor], + ) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + if self.step_index is None: + self._init_step_index(timestep) + + sigma = self.sigmas[self.step_index] + sample = sample / ((sigma**2 + 1) ** 0.5) + return sample + + def set_timesteps( + self, + num_inference_steps: Optional[int] = None, + device: Union[str, torch.device] = None, + num_train_timesteps: Optional[int] = None, + timesteps: Optional[List[int]] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + num_train_timesteps (`int`, *optional*): + The number of diffusion steps used when training the model. If `None`, the default + `num_train_timesteps` attribute is used. + timesteps (`List[int]`, *optional*): + Custom timesteps used to support arbitrary spacing between timesteps. If `None`, timesteps will be + generated based on the `timestep_spacing` attribute. If `timesteps` is passed, `num_inference_steps` + must be `None`, and `timestep_spacing` attribute will be ignored. + """ + if num_inference_steps is None and timesteps is None: + raise ValueError("Must pass exactly one of `num_inference_steps` or `custom_timesteps`.") + if num_inference_steps is not None and timesteps is not None: + raise ValueError("Can only pass one of `num_inference_steps` or `custom_timesteps`.") + if timesteps is not None and self.config.use_karras_sigmas: + raise ValueError("Cannot use `timesteps` with `config.use_karras_sigmas = True`") + if timesteps is not None and self.config.use_exponential_sigmas: + raise ValueError("Cannot set `timesteps` with `config.use_exponential_sigmas = True`.") + if timesteps is not None and self.config.use_beta_sigmas: + raise ValueError("Cannot set `timesteps` with `config.use_beta_sigmas = True`.") + + num_inference_steps = num_inference_steps or len(timesteps) + self.num_inference_steps = num_inference_steps + num_train_timesteps = num_train_timesteps or self.config.num_train_timesteps + + if timesteps is not None: + timesteps = np.array(timesteps, dtype=np.float32) + else: + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = np.linspace(0, num_train_timesteps - 1, num_inference_steps, dtype=np.float32)[::-1].copy() + elif self.config.timestep_spacing == "leading": + step_ratio = num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.float32) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(num_train_timesteps, 0, -step_ratio)).round().copy().astype(np.float32) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + log_sigmas = np.log(sigmas) + sigmas = np.interp(timesteps, np.arange(0, len(sigmas)), sigmas) + + if self.config.use_karras_sigmas: + sigmas = self._convert_to_karras(in_sigmas=sigmas, num_inference_steps=self.num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + elif self.config.use_exponential_sigmas: + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + elif self.config.use_beta_sigmas: + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + + sigmas = np.concatenate([sigmas, [0.0]]).astype(np.float32) + sigmas = torch.from_numpy(sigmas).to(device=device) + self.sigmas = torch.cat([sigmas[:1], sigmas[1:-1].repeat_interleave(2), sigmas[-1:]]) + + timesteps = torch.from_numpy(timesteps) + timesteps = torch.cat([timesteps[:1], timesteps[1:].repeat_interleave(2)]) + + self.timesteps = timesteps.to(device=device, dtype=torch.float32) + + # empty dt and derivative + self.prev_derivative = None + self.dt = None + + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._sigma_to_t + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_karras + def _convert_to_karras(self, in_sigmas: torch.Tensor, num_inference_steps) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_exponential + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_beta + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + @property + def state_in_first_order(self): + return self.dt is None + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._init_step_index + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: Union[torch.Tensor, np.ndarray], + timestep: Union[float, torch.Tensor], + sample: Union[torch.Tensor, np.ndarray], + return_dict: bool = True, + ) -> Union[HeunDiscreteSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_heun_discrete.HeunDiscreteSchedulerOutput`] or + tuple. + + Returns: + [`~schedulers.scheduling_heun_discrete.HeunDiscreteSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_heun_discrete.HeunDiscreteSchedulerOutput`] is + returned, otherwise a tuple is returned where the first element is the sample tensor. + """ + if self.step_index is None: + self._init_step_index(timestep) + + if self.state_in_first_order: + sigma = self.sigmas[self.step_index] + sigma_next = self.sigmas[self.step_index + 1] + else: + # 2nd order / Heun's method + sigma = self.sigmas[self.step_index - 1] + sigma_next = self.sigmas[self.step_index] + + # currently only gamma=0 is supported. This usually works best anyways. + # We can support gamma in the future but then need to scale the timestep before + # passing it to the model which requires a change in API + gamma = 0 + sigma_hat = sigma * (gamma + 1) # Note: sigma_hat == sigma for now + + # 1. compute predicted original sample (x_0) from sigma-scaled predicted noise + if self.config.prediction_type == "epsilon": + sigma_input = sigma_hat if self.state_in_first_order else sigma_next + pred_original_sample = sample - sigma_input * model_output + elif self.config.prediction_type == "v_prediction": + sigma_input = sigma_hat if self.state_in_first_order else sigma_next + pred_original_sample = model_output * (-sigma_input / (sigma_input**2 + 1) ** 0.5) + ( + sample / (sigma_input**2 + 1) + ) + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, or `v_prediction`" + ) + + if self.config.clip_sample: + pred_original_sample = pred_original_sample.clamp( + -self.config.clip_sample_range, self.config.clip_sample_range + ) + + if self.state_in_first_order: + # 2. Convert to an ODE derivative for 1st order + derivative = (sample - pred_original_sample) / sigma_hat + # 3. delta timestep + dt = sigma_next - sigma_hat + + # store for 2nd order step + self.prev_derivative = derivative + self.dt = dt + self.sample = sample + else: + # 2. 2nd order / Heun's method + derivative = (sample - pred_original_sample) / sigma_next + derivative = (self.prev_derivative + derivative) / 2 + + # 3. take prev timestep & sample + dt = self.dt + sample = self.sample + + # free dt and derivative + # Note, this puts the scheduler in "first order mode" + self.prev_derivative = None + self.dt = None + self.sample = None + + prev_sample = sample + derivative * dt + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return ( + prev_sample, + pred_original_sample, + ) + + return HeunDiscreteSchedulerOutput(prev_sample=prev_sample, pred_original_sample=pred_original_sample) + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.Tensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # self.begin_index is None when scheduler is used for training, or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + noisy_samples = original_samples + noise * sigma + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ipndm.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ipndm.py new file mode 100644 index 0000000000000000000000000000000000000000..426e7f8cc5150e0660d762a78aa5e8ee4396a2bd --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_ipndm.py @@ -0,0 +1,224 @@ +# Copyright 2024 Zhejiang University Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from .scheduling_utils import SchedulerMixin, SchedulerOutput + + +class IPNDMScheduler(SchedulerMixin, ConfigMixin): + """ + A fourth-order Improved Pseudo Linear Multistep scheduler. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + """ + + order = 1 + + @register_to_config + def __init__( + self, num_train_timesteps: int = 1000, trained_betas: Optional[Union[np.ndarray, List[float]]] = None + ): + # set `betas`, `alphas`, `timesteps` + self.set_timesteps(num_train_timesteps) + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # For now we only support F-PNDM, i.e. the runge-kutta method + # For more information on the algorithm please take a look at the paper: https://huggingface.co/papers/2202.09778 + # mainly at formula (9), (12), (13) and the Algorithm 2. + self.pndm_order = 4 + + # running values + self.ets = [] + self._step_index = None + self._begin_index = None + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + self.num_inference_steps = num_inference_steps + steps = torch.linspace(1, 0, num_inference_steps + 1)[:-1] + steps = torch.cat([steps, torch.tensor([0.0])]) + + if self.config.trained_betas is not None: + self.betas = torch.tensor(self.config.trained_betas, dtype=torch.float32) + else: + self.betas = torch.sin(steps * math.pi / 2) ** 2 + + self.alphas = (1.0 - self.betas**2) ** 0.5 + + timesteps = (torch.atan2(self.betas, self.alphas) / math.pi * 2)[:-1] + self.timesteps = timesteps.to(device) + + self.ets = [] + self._step_index = None + self._begin_index = None + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._init_step_index + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.Tensor, + timestep: Union[int, torch.Tensor], + sample: torch.Tensor, + return_dict: bool = True, + ) -> Union[SchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the sample with + the linear multistep method. It performs one forward pass multiple times to approximate the solution. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_utils.SchedulerOutput`] or tuple. + + Returns: + [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_utils.SchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + if self.step_index is None: + self._init_step_index(timestep) + + timestep_index = self.step_index + prev_timestep_index = self.step_index + 1 + + ets = sample * self.betas[timestep_index] + model_output * self.alphas[timestep_index] + self.ets.append(ets) + + if len(self.ets) == 1: + ets = self.ets[-1] + elif len(self.ets) == 2: + ets = (3 * self.ets[-1] - self.ets[-2]) / 2 + elif len(self.ets) == 3: + ets = (23 * self.ets[-1] - 16 * self.ets[-2] + 5 * self.ets[-3]) / 12 + else: + ets = (1 / 24) * (55 * self.ets[-1] - 59 * self.ets[-2] + 37 * self.ets[-3] - 9 * self.ets[-4]) + + prev_sample = self._get_prev_sample(sample, timestep_index, prev_timestep_index, ets) + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return (prev_sample,) + + return SchedulerOutput(prev_sample=prev_sample) + + def scale_model_input(self, sample: torch.Tensor, *args, **kwargs) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + def _get_prev_sample(self, sample, timestep_index, prev_timestep_index, ets): + alpha = self.alphas[timestep_index] + sigma = self.betas[timestep_index] + + next_alpha = self.alphas[prev_timestep_index] + next_sigma = self.betas[prev_timestep_index] + + pred = (sample - sigma * ets) / max(alpha, 1e-8) + prev_sample = next_alpha * pred + ets * next_sigma + + return prev_sample + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_k_dpm_2_ancestral_discrete.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_k_dpm_2_ancestral_discrete.py new file mode 100644 index 0000000000000000000000000000000000000000..2085be82da5d895c7533e67bd6d9330901f2c2f7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_k_dpm_2_ancestral_discrete.py @@ -0,0 +1,617 @@ +# Copyright 2024 Katherine Crowson, The HuggingFace Team and hlky. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput, is_scipy_available +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin + + +if is_scipy_available(): + import scipy.stats + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->KDPM2AncestralDiscrete +class KDPM2AncestralDiscreteSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +class KDPM2AncestralDiscreteScheduler(SchedulerMixin, ConfigMixin): + """ + KDPM2DiscreteScheduler with ancestral sampling is inspired by the DPMSolver2 and Algorithm 2 from the [Elucidating + the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.00085): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.012): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear` or `scaled_linear`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + use_karras_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use Karras sigmas for step sizes in the noise schedule during the sampling process. If `True`, + the sigmas are determined according to a sequence of noise levels {σi}. + use_exponential_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use exponential sigmas for step sizes in the noise schedule during the sampling process. + use_beta_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use beta sigmas for step sizes in the noise schedule during the sampling process. Refer to [Beta + Sampling is All You Need](https://huggingface.co/papers/2407.12173) for more information. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 2 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.00085, # sensible defaults + beta_end: float = 0.012, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + prediction_type: str = "epsilon", + timestep_spacing: str = "linspace", + steps_offset: int = 0, + ): + if self.config.use_beta_sigmas and not is_scipy_available(): + raise ImportError("Make sure to install scipy if you want to use beta sigmas.") + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + # set all values + self.set_timesteps(num_train_timesteps, None, num_train_timesteps) + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def init_noise_sigma(self): + # standard deviation of the initial noise distribution + if self.config.timestep_spacing in ["linspace", "trailing"]: + return self.sigmas.max() + + return (self.sigmas.max() ** 2 + 1) ** 0.5 + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def scale_model_input( + self, + sample: torch.Tensor, + timestep: Union[float, torch.Tensor], + ) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + if self.step_index is None: + self._init_step_index(timestep) + + if self.state_in_first_order: + sigma = self.sigmas[self.step_index] + else: + sigma = self.sigmas_interpol[self.step_index - 1] + + sample = sample / ((sigma**2 + 1) ** 0.5) + return sample + + def set_timesteps( + self, + num_inference_steps: int, + device: Union[str, torch.device] = None, + num_train_timesteps: Optional[int] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + self.num_inference_steps = num_inference_steps + + num_train_timesteps = num_train_timesteps or self.config.num_train_timesteps + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = np.linspace(0, num_train_timesteps - 1, num_inference_steps, dtype=np.float32)[::-1].copy() + elif self.config.timestep_spacing == "leading": + step_ratio = num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.float32) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(num_train_timesteps, 0, -step_ratio)).round().copy().astype(np.float32) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + log_sigmas = np.log(sigmas) + + sigmas = np.interp(timesteps, np.arange(0, len(sigmas)), sigmas) + + if self.config.use_karras_sigmas: + sigmas = self._convert_to_karras(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]).round() + elif self.config.use_exponential_sigmas: + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + elif self.config.use_beta_sigmas: + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + + self.log_sigmas = torch.from_numpy(log_sigmas).to(device) + sigmas = np.concatenate([sigmas, [0.0]]).astype(np.float32) + sigmas = torch.from_numpy(sigmas).to(device=device) + + # compute up and down sigmas + sigmas_next = sigmas.roll(-1) + sigmas_next[-1] = 0.0 + sigmas_up = (sigmas_next**2 * (sigmas**2 - sigmas_next**2) / sigmas**2) ** 0.5 + sigmas_down = (sigmas_next**2 - sigmas_up**2) ** 0.5 + sigmas_down[-1] = 0.0 + + # compute interpolated sigmas + sigmas_interpol = sigmas.log().lerp(sigmas_down.log(), 0.5).exp() + sigmas_interpol[-2:] = 0.0 + + # set sigmas + self.sigmas = torch.cat([sigmas[:1], sigmas[1:].repeat_interleave(2), sigmas[-1:]]) + self.sigmas_interpol = torch.cat( + [sigmas_interpol[:1], sigmas_interpol[1:].repeat_interleave(2), sigmas_interpol[-1:]] + ) + self.sigmas_up = torch.cat([sigmas_up[:1], sigmas_up[1:].repeat_interleave(2), sigmas_up[-1:]]) + self.sigmas_down = torch.cat([sigmas_down[:1], sigmas_down[1:].repeat_interleave(2), sigmas_down[-1:]]) + + if str(device).startswith("mps"): + timesteps = torch.from_numpy(timesteps).to(device, dtype=torch.float32) + else: + timesteps = torch.from_numpy(timesteps).to(device) + + sigmas_interpol = sigmas_interpol.cpu() + log_sigmas = self.log_sigmas.cpu() + timesteps_interpol = np.array( + [self._sigma_to_t(sigma_interpol, log_sigmas) for sigma_interpol in sigmas_interpol] + ) + + timesteps_interpol = torch.from_numpy(timesteps_interpol).to(device, dtype=timesteps.dtype) + interleaved_timesteps = torch.stack((timesteps_interpol[:-2, None], timesteps[1:, None]), dim=-1).flatten() + + self.timesteps = torch.cat([timesteps[:1], interleaved_timesteps]) + + self.sample = None + + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._sigma_to_t + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_karras + def _convert_to_karras(self, in_sigmas: torch.Tensor, num_inference_steps) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_exponential + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_beta + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + @property + def state_in_first_order(self): + return self.sample is None + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._init_step_index + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: Union[torch.Tensor, np.ndarray], + timestep: Union[float, torch.Tensor], + sample: Union[torch.Tensor, np.ndarray], + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[KDPM2AncestralDiscreteSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`): + Whether or not to return a + [`~schedulers.scheduling_k_dpm_2_ancestral_discrete.KDPM2AncestralDiscreteSchedulerOutput`] or tuple. + + Returns: + [`~schedulers.scheduling_k_dpm_2_ancestral_discrete.KDPM2AncestralDiscreteSchedulerOutput`] or `tuple`: + If return_dict is `True`, + [`~schedulers.scheduling_k_dpm_2_ancestral_discrete.KDPM2AncestralDiscreteSchedulerOutput`] is + returned, otherwise a tuple is returned where the first element is the sample tensor. + """ + if self.step_index is None: + self._init_step_index(timestep) + + if self.state_in_first_order: + sigma = self.sigmas[self.step_index] + sigma_interpol = self.sigmas_interpol[self.step_index] + sigma_up = self.sigmas_up[self.step_index] + sigma_down = self.sigmas_down[self.step_index - 1] + else: + # 2nd order / KPDM2's method + sigma = self.sigmas[self.step_index - 1] + sigma_interpol = self.sigmas_interpol[self.step_index - 1] + sigma_up = self.sigmas_up[self.step_index - 1] + sigma_down = self.sigmas_down[self.step_index - 1] + + # currently only gamma=0 is supported. This usually works best anyways. + # We can support gamma in the future but then need to scale the timestep before + # passing it to the model which requires a change in API + gamma = 0 + sigma_hat = sigma * (gamma + 1) # Note: sigma_hat == sigma for now + + # 1. compute predicted original sample (x_0) from sigma-scaled predicted noise + if self.config.prediction_type == "epsilon": + sigma_input = sigma_hat if self.state_in_first_order else sigma_interpol + pred_original_sample = sample - sigma_input * model_output + elif self.config.prediction_type == "v_prediction": + sigma_input = sigma_hat if self.state_in_first_order else sigma_interpol + pred_original_sample = model_output * (-sigma_input / (sigma_input**2 + 1) ** 0.5) + ( + sample / (sigma_input**2 + 1) + ) + elif self.config.prediction_type == "sample": + raise NotImplementedError("prediction_type not implemented yet: sample") + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, or `v_prediction`" + ) + + if self.state_in_first_order: + # 2. Convert to an ODE derivative for 1st order + derivative = (sample - pred_original_sample) / sigma_hat + # 3. delta timestep + dt = sigma_interpol - sigma_hat + + # store for 2nd order step + self.sample = sample + self.dt = dt + prev_sample = sample + derivative * dt + else: + # DPM-Solver-2 + # 2. Convert to an ODE derivative for 2nd order + derivative = (sample - pred_original_sample) / sigma_interpol + # 3. delta timestep + dt = sigma_down - sigma_hat + + sample = self.sample + self.sample = None + + prev_sample = sample + derivative * dt + noise = randn_tensor( + model_output.shape, dtype=model_output.dtype, device=model_output.device, generator=generator + ) + prev_sample = prev_sample + noise * sigma_up + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return ( + prev_sample, + pred_original_sample, + ) + + return KDPM2AncestralDiscreteSchedulerOutput( + prev_sample=prev_sample, pred_original_sample=pred_original_sample + ) + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.Tensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # self.begin_index is None when scheduler is used for training, or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + noisy_samples = original_samples + noise * sigma + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_k_dpm_2_discrete.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_k_dpm_2_discrete.py new file mode 100644 index 0000000000000000000000000000000000000000..db7f19c3b4bc532f984110a09ff6faa9f2374761 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_k_dpm_2_discrete.py @@ -0,0 +1,589 @@ +# Copyright 2024 Katherine Crowson, The HuggingFace Team and hlky. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput, is_scipy_available +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin + + +if is_scipy_available(): + import scipy.stats + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->KDPM2Discrete +class KDPM2DiscreteSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +class KDPM2DiscreteScheduler(SchedulerMixin, ConfigMixin): + """ + KDPM2DiscreteScheduler is inspired by the DPMSolver2 and Algorithm 2 from the [Elucidating the Design Space of + Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.00085): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.012): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear` or `scaled_linear`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + use_karras_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use Karras sigmas for step sizes in the noise schedule during the sampling process. If `True`, + the sigmas are determined according to a sequence of noise levels {σi}. + use_exponential_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use exponential sigmas for step sizes in the noise schedule during the sampling process. + use_beta_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use beta sigmas for step sizes in the noise schedule during the sampling process. Refer to [Beta + Sampling is All You Need](https://huggingface.co/papers/2407.12173) for more information. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 2 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.00085, # sensible defaults + beta_end: float = 0.012, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + prediction_type: str = "epsilon", + timestep_spacing: str = "linspace", + steps_offset: int = 0, + ): + if self.config.use_beta_sigmas and not is_scipy_available(): + raise ImportError("Make sure to install scipy if you want to use beta sigmas.") + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + # set all values + self.set_timesteps(num_train_timesteps, None, num_train_timesteps) + + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def init_noise_sigma(self): + # standard deviation of the initial noise distribution + if self.config.timestep_spacing in ["linspace", "trailing"]: + return self.sigmas.max() + + return (self.sigmas.max() ** 2 + 1) ** 0.5 + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def scale_model_input( + self, + sample: torch.Tensor, + timestep: Union[float, torch.Tensor], + ) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + if self.step_index is None: + self._init_step_index(timestep) + + if self.state_in_first_order: + sigma = self.sigmas[self.step_index] + else: + sigma = self.sigmas_interpol[self.step_index] + + sample = sample / ((sigma**2 + 1) ** 0.5) + return sample + + def set_timesteps( + self, + num_inference_steps: int, + device: Union[str, torch.device] = None, + num_train_timesteps: Optional[int] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + self.num_inference_steps = num_inference_steps + + num_train_timesteps = num_train_timesteps or self.config.num_train_timesteps + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = np.linspace(0, num_train_timesteps - 1, num_inference_steps, dtype=np.float32)[::-1].copy() + elif self.config.timestep_spacing == "leading": + step_ratio = num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.float32) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(num_train_timesteps, 0, -step_ratio)).round().copy().astype(np.float32) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + log_sigmas = np.log(sigmas) + sigmas = np.interp(timesteps, np.arange(0, len(sigmas)), sigmas) + + if self.config.use_karras_sigmas: + sigmas = self._convert_to_karras(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]).round() + elif self.config.use_exponential_sigmas: + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + elif self.config.use_beta_sigmas: + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + + self.log_sigmas = torch.from_numpy(log_sigmas).to(device=device) + sigmas = np.concatenate([sigmas, [0.0]]).astype(np.float32) + sigmas = torch.from_numpy(sigmas).to(device=device) + + # interpolate sigmas + sigmas_interpol = sigmas.log().lerp(sigmas.roll(1).log(), 0.5).exp() + + self.sigmas = torch.cat([sigmas[:1], sigmas[1:].repeat_interleave(2), sigmas[-1:]]) + self.sigmas_interpol = torch.cat( + [sigmas_interpol[:1], sigmas_interpol[1:].repeat_interleave(2), sigmas_interpol[-1:]] + ) + + timesteps = torch.from_numpy(timesteps).to(device) + + # interpolate timesteps + sigmas_interpol = sigmas_interpol.cpu() + log_sigmas = self.log_sigmas.cpu() + timesteps_interpol = np.array( + [self._sigma_to_t(sigma_interpol, log_sigmas) for sigma_interpol in sigmas_interpol] + ) + timesteps_interpol = torch.from_numpy(timesteps_interpol).to(device, dtype=timesteps.dtype) + interleaved_timesteps = torch.stack((timesteps_interpol[1:-1, None], timesteps[1:, None]), dim=-1).flatten() + + self.timesteps = torch.cat([timesteps[:1], interleaved_timesteps]) + + self.sample = None + + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def state_in_first_order(self): + return self.sample is None + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._init_step_index + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._sigma_to_t + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_karras + def _convert_to_karras(self, in_sigmas: torch.Tensor, num_inference_steps) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_exponential + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_beta + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + def step( + self, + model_output: Union[torch.Tensor, np.ndarray], + timestep: Union[float, torch.Tensor], + sample: Union[torch.Tensor, np.ndarray], + return_dict: bool = True, + ) -> Union[KDPM2DiscreteSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_k_dpm_2_discrete.KDPM2DiscreteSchedulerOutput`] or + tuple. + + Returns: + [`~schedulers.scheduling_k_dpm_2_discrete.KDPM2DiscreteSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_k_dpm_2_discrete.KDPM2DiscreteSchedulerOutput`] is + returned, otherwise a tuple is returned where the first element is the sample tensor. + """ + if self.step_index is None: + self._init_step_index(timestep) + + if self.state_in_first_order: + sigma = self.sigmas[self.step_index] + sigma_interpol = self.sigmas_interpol[self.step_index + 1] + sigma_next = self.sigmas[self.step_index + 1] + else: + # 2nd order / KDPM2's method + sigma = self.sigmas[self.step_index - 1] + sigma_interpol = self.sigmas_interpol[self.step_index] + sigma_next = self.sigmas[self.step_index] + + # currently only gamma=0 is supported. This usually works best anyways. + # We can support gamma in the future but then need to scale the timestep before + # passing it to the model which requires a change in API + gamma = 0 + sigma_hat = sigma * (gamma + 1) # Note: sigma_hat == sigma for now + + # 1. compute predicted original sample (x_0) from sigma-scaled predicted noise + if self.config.prediction_type == "epsilon": + sigma_input = sigma_hat if self.state_in_first_order else sigma_interpol + pred_original_sample = sample - sigma_input * model_output + elif self.config.prediction_type == "v_prediction": + sigma_input = sigma_hat if self.state_in_first_order else sigma_interpol + pred_original_sample = model_output * (-sigma_input / (sigma_input**2 + 1) ** 0.5) + ( + sample / (sigma_input**2 + 1) + ) + elif self.config.prediction_type == "sample": + raise NotImplementedError("prediction_type not implemented yet: sample") + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, or `v_prediction`" + ) + + if self.state_in_first_order: + # 2. Convert to an ODE derivative for 1st order + derivative = (sample - pred_original_sample) / sigma_hat + # 3. delta timestep + dt = sigma_interpol - sigma_hat + + # store for 2nd order step + self.sample = sample + else: + # DPM-Solver-2 + # 2. Convert to an ODE derivative for 2nd order + derivative = (sample - pred_original_sample) / sigma_interpol + + # 3. delta timestep + dt = sigma_next - sigma_hat + + sample = self.sample + self.sample = None + + # upon completion increase step index by one + self._step_index += 1 + + prev_sample = sample + derivative * dt + + if not return_dict: + return ( + prev_sample, + pred_original_sample, + ) + + return KDPM2DiscreteSchedulerOutput(prev_sample=prev_sample, pred_original_sample=pred_original_sample) + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.Tensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # self.begin_index is None when scheduler is used for training, or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + noisy_samples = original_samples + noise * sigma + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_karras_ve_flax.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_karras_ve_flax.py new file mode 100644 index 0000000000000000000000000000000000000000..f68f89d433f84ca7a107f3f020de2d14ce9efcb7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_karras_ve_flax.py @@ -0,0 +1,238 @@ +# Copyright 2024 NVIDIA and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import flax +import jax +import jax.numpy as jnp +from jax import random + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from .scheduling_utils_flax import FlaxSchedulerMixin + + +@flax.struct.dataclass +class KarrasVeSchedulerState: + # setable values + num_inference_steps: Optional[int] = None + timesteps: Optional[jnp.ndarray] = None + schedule: Optional[jnp.ndarray] = None # sigma(t_i) + + @classmethod + def create(cls): + return cls() + + +@dataclass +class FlaxKarrasVeOutput(BaseOutput): + """ + Output class for the scheduler's step function output. + + Args: + prev_sample (`jnp.ndarray` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample (x_{t-1}) of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + derivative (`jnp.ndarray` of shape `(batch_size, num_channels, height, width)` for images): + Derivative of predicted original image sample (x_0). + state (`KarrasVeSchedulerState`): the `FlaxKarrasVeScheduler` state data class. + """ + + prev_sample: jnp.ndarray + derivative: jnp.ndarray + state: KarrasVeSchedulerState + + +class FlaxKarrasVeScheduler(FlaxSchedulerMixin, ConfigMixin): + """ + Stochastic sampling from Karras et al. [1] tailored to the Variance-Expanding (VE) models [2]. Use Algorithm 2 and + the VE column of Table 1 from [1] for reference. + + [1] Karras, Tero, et al. "Elucidating the Design Space of Diffusion-Based Generative Models." + https://huggingface.co/papers/2206.00364 [2] Song, Yang, et al. "Score-based generative modeling through stochastic + differential equations." https://huggingface.co/papers/2011.13456 + + [`~ConfigMixin`] takes care of storing all config attributes that are passed in the scheduler's `__init__` + function, such as `num_train_timesteps`. They can be accessed via `scheduler.config.num_train_timesteps`. + [`SchedulerMixin`] provides general loading and saving functionality via the [`SchedulerMixin.save_pretrained`] and + [`~SchedulerMixin.from_pretrained`] functions. + + For more details on the parameters, see the original paper's Appendix E.: "Elucidating the Design Space of + Diffusion-Based Generative Models." https://huggingface.co/papers/2206.00364. The grid search values used to find + the optimal {s_noise, s_churn, s_min, s_max} for a specific model are described in Table 5 of the paper. + + Args: + sigma_min (`float`): minimum noise magnitude + sigma_max (`float`): maximum noise magnitude + s_noise (`float`): the amount of additional noise to counteract loss of detail during sampling. + A reasonable range is [1.000, 1.011]. + s_churn (`float`): the parameter controlling the overall amount of stochasticity. + A reasonable range is [0, 100]. + s_min (`float`): the start value of the sigma range where we add noise (enable stochasticity). + A reasonable range is [0, 10]. + s_max (`float`): the end value of the sigma range where we add noise. + A reasonable range is [0.2, 80]. + """ + + @property + def has_state(self): + return True + + @register_to_config + def __init__( + self, + sigma_min: float = 0.02, + sigma_max: float = 100, + s_noise: float = 1.007, + s_churn: float = 80, + s_min: float = 0.05, + s_max: float = 50, + ): + pass + + def create_state(self): + return KarrasVeSchedulerState.create() + + def set_timesteps( + self, state: KarrasVeSchedulerState, num_inference_steps: int, shape: Tuple = () + ) -> KarrasVeSchedulerState: + """ + Sets the continuous timesteps used for the diffusion chain. Supporting function to be run before inference. + + Args: + state (`KarrasVeSchedulerState`): + the `FlaxKarrasVeScheduler` state data class. + num_inference_steps (`int`): + the number of diffusion steps used when generating samples with a pre-trained model. + + """ + timesteps = jnp.arange(0, num_inference_steps)[::-1].copy() + schedule = [ + ( + self.config.sigma_max**2 + * (self.config.sigma_min**2 / self.config.sigma_max**2) ** (i / (num_inference_steps - 1)) + ) + for i in timesteps + ] + + return state.replace( + num_inference_steps=num_inference_steps, + schedule=jnp.array(schedule, dtype=jnp.float32), + timesteps=timesteps, + ) + + def add_noise_to_input( + self, + state: KarrasVeSchedulerState, + sample: jnp.ndarray, + sigma: float, + key: jax.Array, + ) -> Tuple[jnp.ndarray, float]: + """ + Explicit Langevin-like "churn" step of adding noise to the sample according to a factor gamma_i ≥ 0 to reach a + higher noise level sigma_hat = sigma_i + gamma_i*sigma_i. + + TODO Args: + """ + if self.config.s_min <= sigma <= self.config.s_max: + gamma = min(self.config.s_churn / state.num_inference_steps, 2**0.5 - 1) + else: + gamma = 0 + + # sample eps ~ N(0, S_noise^2 * I) + key = random.split(key, num=1) + eps = self.config.s_noise * random.normal(key=key, shape=sample.shape) + sigma_hat = sigma + gamma * sigma + sample_hat = sample + ((sigma_hat**2 - sigma**2) ** 0.5 * eps) + + return sample_hat, sigma_hat + + def step( + self, + state: KarrasVeSchedulerState, + model_output: jnp.ndarray, + sigma_hat: float, + sigma_prev: float, + sample_hat: jnp.ndarray, + return_dict: bool = True, + ) -> Union[FlaxKarrasVeOutput, Tuple]: + """ + Predict the sample at the previous timestep by reversing the SDE. Core function to propagate the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + state (`KarrasVeSchedulerState`): the `FlaxKarrasVeScheduler` state data class. + model_output (`torch.Tensor` or `np.ndarray`): direct output from learned diffusion model. + sigma_hat (`float`): TODO + sigma_prev (`float`): TODO + sample_hat (`torch.Tensor` or `np.ndarray`): TODO + return_dict (`bool`): option for returning tuple rather than FlaxKarrasVeOutput class + + Returns: + [`~schedulers.scheduling_karras_ve_flax.FlaxKarrasVeOutput`] or `tuple`: Updated sample in the diffusion + chain and derivative. [`~schedulers.scheduling_karras_ve_flax.FlaxKarrasVeOutput`] if `return_dict` is + True, otherwise a `tuple`. When returning a tuple, the first element is the sample tensor. + """ + + pred_original_sample = sample_hat + sigma_hat * model_output + derivative = (sample_hat - pred_original_sample) / sigma_hat + sample_prev = sample_hat + (sigma_prev - sigma_hat) * derivative + + if not return_dict: + return (sample_prev, derivative, state) + + return FlaxKarrasVeOutput(prev_sample=sample_prev, derivative=derivative, state=state) + + def step_correct( + self, + state: KarrasVeSchedulerState, + model_output: jnp.ndarray, + sigma_hat: float, + sigma_prev: float, + sample_hat: jnp.ndarray, + sample_prev: jnp.ndarray, + derivative: jnp.ndarray, + return_dict: bool = True, + ) -> Union[FlaxKarrasVeOutput, Tuple]: + """ + Correct the predicted sample based on the output model_output of the network. TODO complete description + + Args: + state (`KarrasVeSchedulerState`): the `FlaxKarrasVeScheduler` state data class. + model_output (`torch.Tensor` or `np.ndarray`): direct output from learned diffusion model. + sigma_hat (`float`): TODO + sigma_prev (`float`): TODO + sample_hat (`torch.Tensor` or `np.ndarray`): TODO + sample_prev (`torch.Tensor` or `np.ndarray`): TODO + derivative (`torch.Tensor` or `np.ndarray`): TODO + return_dict (`bool`): option for returning tuple rather than FlaxKarrasVeOutput class + + Returns: + prev_sample (TODO): updated sample in the diffusion chain. derivative (TODO): TODO + + """ + pred_original_sample = sample_prev + sigma_prev * model_output + derivative_corr = (sample_prev - pred_original_sample) / sigma_prev + sample_prev = sample_hat + (sigma_prev - sigma_hat) * (0.5 * derivative + 0.5 * derivative_corr) + + if not return_dict: + return (sample_prev, derivative, state) + + return FlaxKarrasVeOutput(prev_sample=sample_prev, derivative=derivative, state=state) + + def add_noise(self, state: KarrasVeSchedulerState, original_samples, noise, timesteps): + raise NotImplementedError() diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_lcm.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_lcm.py new file mode 100644 index 0000000000000000000000000000000000000000..58735441bc352d49d589a10ad121afa6dbfac167 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_lcm.py @@ -0,0 +1,653 @@ +# Copyright 2024 Stanford University Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This code is strongly influenced by https://github.com/pesser/pytorch_diffusion +# and https://github.com/hojonathanho/diffusion + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput, logging +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import SchedulerMixin + + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + + +@dataclass +class LCMSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + denoised: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +# Copied from diffusers.schedulers.scheduling_ddim.rescale_zero_terminal_snr +def rescale_zero_terminal_snr(betas: torch.Tensor) -> torch.Tensor: + """ + Rescales betas to have zero terminal SNR Based on https://huggingface.co/papers/2305.08891 (Algorithm 1) + + + Args: + betas (`torch.Tensor`): + the betas that the scheduler is being initialized with. + + Returns: + `torch.Tensor`: rescaled betas with zero terminal SNR + """ + # Convert betas to alphas_bar_sqrt + alphas = 1.0 - betas + alphas_cumprod = torch.cumprod(alphas, dim=0) + alphas_bar_sqrt = alphas_cumprod.sqrt() + + # Store old values. + alphas_bar_sqrt_0 = alphas_bar_sqrt[0].clone() + alphas_bar_sqrt_T = alphas_bar_sqrt[-1].clone() + + # Shift so the last timestep is zero. + alphas_bar_sqrt -= alphas_bar_sqrt_T + + # Scale so the first timestep is back to the old value. + alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T) + + # Convert alphas_bar_sqrt to betas + alphas_bar = alphas_bar_sqrt**2 # Revert sqrt + alphas = alphas_bar[1:] / alphas_bar[:-1] # Revert cumprod + alphas = torch.cat([alphas_bar[0:1], alphas]) + betas = 1 - alphas + + return betas + + +class LCMScheduler(SchedulerMixin, ConfigMixin): + """ + `LCMScheduler` extends the denoising procedure introduced in denoising diffusion probabilistic models (DDPMs) with + non-Markovian guidance. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. [`~ConfigMixin`] takes care of storing all config + attributes that are passed in the scheduler's `__init__` function, such as `num_train_timesteps`. They can be + accessed via `scheduler.config.num_train_timesteps`. [`SchedulerMixin`] provides general loading and saving + functionality via the [`SchedulerMixin.save_pretrained`] and [`~SchedulerMixin.from_pretrained`] functions. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + original_inference_steps (`int`, *optional*, defaults to 50): + The default number of inference steps used to generate a linearly-spaced timestep schedule, from which we + will ultimately take `num_inference_steps` evenly spaced timesteps to form the final timestep schedule. + clip_sample (`bool`, defaults to `True`): + Clip the predicted sample for numerical stability. + clip_sample_range (`float`, defaults to 1.0): + The maximum magnitude for sample clipping. Valid only when `clip_sample=True`. + set_alpha_to_one (`bool`, defaults to `True`): + Each diffusion step uses the alphas product value at that step and at the previous one. For the final step + there is no previous alpha. When this option is `True` the previous alpha product is fixed to `1`, + otherwise it uses the alpha value at step 0. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + thresholding (`bool`, defaults to `False`): + Whether to use the "dynamic thresholding" method. This is unsuitable for latent-space diffusion models such + as Stable Diffusion. + dynamic_thresholding_ratio (`float`, defaults to 0.995): + The ratio for the dynamic thresholding method. Valid only when `thresholding=True`. + sample_max_value (`float`, defaults to 1.0): + The threshold value for dynamic thresholding. Valid only when `thresholding=True`. + timestep_spacing (`str`, defaults to `"leading"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + timestep_scaling (`float`, defaults to 10.0): + The factor the timesteps will be multiplied by when calculating the consistency model boundary conditions + `c_skip` and `c_out`. Increasing this will decrease the approximation error (although the approximation + error at the default of `10.0` is already pretty small). + rescale_betas_zero_snr (`bool`, defaults to `False`): + Whether to rescale the betas to have zero terminal SNR. This enables the model to generate very bright and + dark samples instead of limiting it to samples with medium brightness. Loosely related to + [`--offset_noise`](https://github.com/huggingface/diffusers/blob/74fd735eb073eb1d774b1ab4154a0876eb82f055/examples/dreambooth/train_dreambooth.py#L506). + """ + + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.00085, + beta_end: float = 0.012, + beta_schedule: str = "scaled_linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + original_inference_steps: int = 50, + clip_sample: bool = False, + clip_sample_range: float = 1.0, + set_alpha_to_one: bool = True, + steps_offset: int = 0, + prediction_type: str = "epsilon", + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + sample_max_value: float = 1.0, + timestep_spacing: str = "leading", + timestep_scaling: float = 10.0, + rescale_betas_zero_snr: bool = False, + ): + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + # Rescale for zero SNR + if rescale_betas_zero_snr: + self.betas = rescale_zero_terminal_snr(self.betas) + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + # At every step in ddim, we are looking into the previous alphas_cumprod + # For the final step, there is no previous alphas_cumprod because we are already at 0 + # `set_alpha_to_one` decides whether we set this parameter simply to one or + # whether we use the final alpha of the "non-previous" one. + self.final_alpha_cumprod = torch.tensor(1.0) if set_alpha_to_one else self.alphas_cumprod[0] + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # setable values + self.num_inference_steps = None + self.timesteps = torch.from_numpy(np.arange(0, num_train_timesteps)[::-1].copy().astype(np.int64)) + self.custom_timesteps = False + + self._step_index = None + self._begin_index = None + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._init_step_index + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + @property + def step_index(self): + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler._threshold_sample + def _threshold_sample(self, sample: torch.Tensor) -> torch.Tensor: + """ + "Dynamic thresholding: At each sampling step we set s to a certain percentile absolute pixel value in xt0 (the + prediction of x_0 at timestep t), and if s > 1, then we threshold xt0 to the range [-s, s] and then divide by + s. Dynamic thresholding pushes saturated pixels (those near -1 and 1) inwards, thereby actively preventing + pixels from saturation at each step. We find that dynamic thresholding results in significantly better + photorealism as well as better image-text alignment, especially when using very large guidance weights." + + https://huggingface.co/papers/2205.11487 + """ + dtype = sample.dtype + batch_size, channels, *remaining_dims = sample.shape + + if dtype not in (torch.float32, torch.float64): + sample = sample.float() # upcast for quantile calculation, and clamp not implemented for cpu half + + # Flatten sample for doing quantile calculation along each image + sample = sample.reshape(batch_size, channels * np.prod(remaining_dims)) + + abs_sample = sample.abs() # "a certain percentile absolute pixel value" + + s = torch.quantile(abs_sample, self.config.dynamic_thresholding_ratio, dim=1) + s = torch.clamp( + s, min=1, max=self.config.sample_max_value + ) # When clamped to min=1, equivalent to standard clipping to [-1, 1] + s = s.unsqueeze(1) # (batch_size, 1) because clamp will broadcast along dim=0 + sample = torch.clamp(sample, -s, s) / s # "we threshold xt0 to the range [-s, s] and then divide by s" + + sample = sample.reshape(batch_size, channels, *remaining_dims) + sample = sample.to(dtype) + + return sample + + def set_timesteps( + self, + num_inference_steps: Optional[int] = None, + device: Union[str, torch.device] = None, + original_inference_steps: Optional[int] = None, + timesteps: Optional[List[int]] = None, + strength: int = 1.0, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`, *optional*): + The number of diffusion steps used when generating samples with a pre-trained model. If used, + `timesteps` must be `None`. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + original_inference_steps (`int`, *optional*): + The original number of inference steps, which will be used to generate a linearly-spaced timestep + schedule (which is different from the standard `diffusers` implementation). We will then take + `num_inference_steps` timesteps from this schedule, evenly spaced in terms of indices, and use that as + our final timestep schedule. If not set, this will default to the `original_inference_steps` attribute. + timesteps (`List[int]`, *optional*): + Custom timesteps used to support arbitrary spacing between timesteps. If `None`, then the default + timestep spacing strategy of equal spacing between timesteps on the training/distillation timestep + schedule is used. If `timesteps` is passed, `num_inference_steps` must be `None`. + """ + # 0. Check inputs + if num_inference_steps is None and timesteps is None: + raise ValueError("Must pass exactly one of `num_inference_steps` or `custom_timesteps`.") + + if num_inference_steps is not None and timesteps is not None: + raise ValueError("Can only pass one of `num_inference_steps` or `custom_timesteps`.") + + # 1. Calculate the LCM original training/distillation timestep schedule. + original_steps = ( + original_inference_steps if original_inference_steps is not None else self.config.original_inference_steps + ) + + if original_steps > self.config.num_train_timesteps: + raise ValueError( + f"`original_steps`: {original_steps} cannot be larger than `self.config.train_timesteps`:" + f" {self.config.num_train_timesteps} as the unet model trained with this scheduler can only handle" + f" maximal {self.config.num_train_timesteps} timesteps." + ) + + # LCM Timesteps Setting + # The skipping step parameter k from the paper. + k = self.config.num_train_timesteps // original_steps + # LCM Training/Distillation Steps Schedule + # Currently, only a linearly-spaced schedule is supported (same as in the LCM distillation scripts). + lcm_origin_timesteps = np.asarray(list(range(1, int(original_steps * strength) + 1))) * k - 1 + + # 2. Calculate the LCM inference timestep schedule. + if timesteps is not None: + # 2.1 Handle custom timestep schedules. + train_timesteps = set(lcm_origin_timesteps) + non_train_timesteps = [] + for i in range(1, len(timesteps)): + if timesteps[i] >= timesteps[i - 1]: + raise ValueError("`custom_timesteps` must be in descending order.") + + if timesteps[i] not in train_timesteps: + non_train_timesteps.append(timesteps[i]) + + if timesteps[0] >= self.config.num_train_timesteps: + raise ValueError( + f"`timesteps` must start before `self.config.train_timesteps`: {self.config.num_train_timesteps}." + ) + + # Raise warning if timestep schedule does not start with self.config.num_train_timesteps - 1 + if strength == 1.0 and timesteps[0] != self.config.num_train_timesteps - 1: + logger.warning( + f"The first timestep on the custom timestep schedule is {timesteps[0]}, not" + f" `self.config.num_train_timesteps - 1`: {self.config.num_train_timesteps - 1}. You may get" + f" unexpected results when using this timestep schedule." + ) + + # Raise warning if custom timestep schedule contains timesteps not on original timestep schedule + if non_train_timesteps: + logger.warning( + f"The custom timestep schedule contains the following timesteps which are not on the original" + f" training/distillation timestep schedule: {non_train_timesteps}. You may get unexpected results" + f" when using this timestep schedule." + ) + + # Raise warning if custom timestep schedule is longer than original_steps + if len(timesteps) > original_steps: + logger.warning( + f"The number of timesteps in the custom timestep schedule is {len(timesteps)}, which exceeds the" + f" the length of the timestep schedule used for training: {original_steps}. You may get some" + f" unexpected results when using this timestep schedule." + ) + + timesteps = np.array(timesteps, dtype=np.int64) + self.num_inference_steps = len(timesteps) + self.custom_timesteps = True + + # Apply strength (e.g. for img2img pipelines) (see StableDiffusionImg2ImgPipeline.get_timesteps) + init_timestep = min(int(self.num_inference_steps * strength), self.num_inference_steps) + t_start = max(self.num_inference_steps - init_timestep, 0) + timesteps = timesteps[t_start * self.order :] + # TODO: also reset self.num_inference_steps? + else: + # 2.2 Create the "standard" LCM inference timestep schedule. + if num_inference_steps > self.config.num_train_timesteps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `self.config.train_timesteps`:" + f" {self.config.num_train_timesteps} as the unet model trained with this scheduler can only handle" + f" maximal {self.config.num_train_timesteps} timesteps." + ) + + skipping_step = len(lcm_origin_timesteps) // num_inference_steps + + if skipping_step < 1: + raise ValueError( + f"The combination of `original_steps x strength`: {original_steps} x {strength} is smaller than `num_inference_steps`: {num_inference_steps}. Make sure to either reduce `num_inference_steps` to a value smaller than {int(original_steps * strength)} or increase `strength` to a value higher than {float(num_inference_steps / original_steps)}." + ) + + self.num_inference_steps = num_inference_steps + + if num_inference_steps > original_steps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `original_inference_steps`:" + f" {original_steps} because the final timestep schedule will be a subset of the" + f" `original_inference_steps`-sized initial timestep schedule." + ) + + # LCM Inference Steps Schedule + lcm_origin_timesteps = lcm_origin_timesteps[::-1].copy() + # Select (approximately) evenly spaced indices from lcm_origin_timesteps. + inference_indices = np.linspace(0, len(lcm_origin_timesteps), num=num_inference_steps, endpoint=False) + inference_indices = np.floor(inference_indices).astype(np.int64) + timesteps = lcm_origin_timesteps[inference_indices] + + self.timesteps = torch.from_numpy(timesteps).to(device=device, dtype=torch.long) + + self._step_index = None + self._begin_index = None + + def get_scalings_for_boundary_condition_discrete(self, timestep): + self.sigma_data = 0.5 # Default: 0.5 + scaled_timestep = timestep * self.config.timestep_scaling + + c_skip = self.sigma_data**2 / (scaled_timestep**2 + self.sigma_data**2) + c_out = scaled_timestep / (scaled_timestep**2 + self.sigma_data**2) ** 0.5 + return c_skip, c_out + + def step( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[LCMSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_lcm.LCMSchedulerOutput`] or `tuple`. + Returns: + [`~schedulers.scheduling_utils.LCMSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_lcm.LCMSchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + if self.step_index is None: + self._init_step_index(timestep) + + # 1. get previous step value + prev_step_index = self.step_index + 1 + if prev_step_index < len(self.timesteps): + prev_timestep = self.timesteps[prev_step_index] + else: + prev_timestep = timestep + + # 2. compute alphas, betas + alpha_prod_t = self.alphas_cumprod[timestep] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + # 3. Get scalings for boundary conditions + c_skip, c_out = self.get_scalings_for_boundary_condition_discrete(timestep) + + # 4. Compute the predicted original sample x_0 based on the model parameterization + if self.config.prediction_type == "epsilon": # noise-prediction + predicted_original_sample = (sample - beta_prod_t.sqrt() * model_output) / alpha_prod_t.sqrt() + elif self.config.prediction_type == "sample": # x-prediction + predicted_original_sample = model_output + elif self.config.prediction_type == "v_prediction": # v-prediction + predicted_original_sample = alpha_prod_t.sqrt() * sample - beta_prod_t.sqrt() * model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample` or" + " `v_prediction` for `LCMScheduler`." + ) + + # 5. Clip or threshold "predicted x_0" + if self.config.thresholding: + predicted_original_sample = self._threshold_sample(predicted_original_sample) + elif self.config.clip_sample: + predicted_original_sample = predicted_original_sample.clamp( + -self.config.clip_sample_range, self.config.clip_sample_range + ) + + # 6. Denoise model output using boundary conditions + denoised = c_out * predicted_original_sample + c_skip * sample + + # 7. Sample and inject noise z ~ N(0, I) for MultiStep Inference + # Noise is not used on the final timestep of the timestep schedule. + # This also means that noise is not used for one-step sampling. + if self.step_index != self.num_inference_steps - 1: + noise = randn_tensor( + model_output.shape, generator=generator, device=model_output.device, dtype=denoised.dtype + ) + prev_sample = alpha_prod_t_prev.sqrt() * denoised + beta_prod_t_prev.sqrt() * noise + else: + prev_sample = denoised + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return (prev_sample, denoised) + + return LCMSchedulerOutput(prev_sample=prev_sample, denoised=denoised) + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as original_samples + # Move the self.alphas_cumprod to device to avoid redundant CPU to GPU data movement + # for the subsequent add_noise calls + self.alphas_cumprod = self.alphas_cumprod.to(device=original_samples.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=original_samples.dtype) + timesteps = timesteps.to(original_samples.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(original_samples.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(original_samples.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + noisy_samples = sqrt_alpha_prod * original_samples + sqrt_one_minus_alpha_prod * noise + return noisy_samples + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.get_velocity + def get_velocity(self, sample: torch.Tensor, noise: torch.Tensor, timesteps: torch.IntTensor) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as sample + self.alphas_cumprod = self.alphas_cumprod.to(device=sample.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=sample.dtype) + timesteps = timesteps.to(sample.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(sample.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(sample.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + velocity = sqrt_alpha_prod * noise - sqrt_one_minus_alpha_prod * sample + return velocity + + def __len__(self): + return self.config.num_train_timesteps + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.previous_timestep + def previous_timestep(self, timestep): + if self.custom_timesteps or self.num_inference_steps: + index = (self.timesteps == timestep).nonzero(as_tuple=True)[0][0] + if index == self.timesteps.shape[0] - 1: + prev_t = torch.tensor(-1) + else: + prev_t = self.timesteps[index + 1] + else: + prev_t = timestep - 1 + return prev_t diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_lms_discrete.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_lms_discrete.py new file mode 100644 index 0000000000000000000000000000000000000000..3f4c6140aedf42c1dac19aa2981e130e436418f0 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_lms_discrete.py @@ -0,0 +1,552 @@ +# Copyright 2024 Katherine Crowson and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import math +import warnings +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import scipy.stats +import torch +from scipy import integrate + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->LMSDiscrete +class LMSDiscreteSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +class LMSDiscreteScheduler(SchedulerMixin, ConfigMixin): + """ + A linear multistep scheduler for discrete beta schedules. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear` or `scaled_linear`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + use_karras_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use Karras sigmas for step sizes in the noise schedule during the sampling process. If `True`, + the sigmas are determined according to a sequence of noise levels {σi}. + use_exponential_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use exponential sigmas for step sizes in the noise schedule during the sampling process. + use_beta_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use beta sigmas for step sizes in the noise schedule during the sampling process. Refer to [Beta + Sampling is All You Need](https://huggingface.co/papers/2407.12173) for more information. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + prediction_type: str = "epsilon", + timestep_spacing: str = "linspace", + steps_offset: int = 0, + ): + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + sigmas = np.concatenate([sigmas[::-1], [0.0]]).astype(np.float32) + self.sigmas = torch.from_numpy(sigmas) + + # setable values + self.num_inference_steps = None + self.use_karras_sigmas = use_karras_sigmas + self.set_timesteps(num_train_timesteps, None) + self.derivatives = [] + self.is_scale_input_called = False + + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def init_noise_sigma(self): + # standard deviation of the initial noise distribution + if self.config.timestep_spacing in ["linspace", "trailing"]: + return self.sigmas.max() + + return (self.sigmas.max() ** 2 + 1) ** 0.5 + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def scale_model_input(self, sample: torch.Tensor, timestep: Union[float, torch.Tensor]) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`float` or `torch.Tensor`): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + + if self.step_index is None: + self._init_step_index(timestep) + + sigma = self.sigmas[self.step_index] + sample = sample / ((sigma**2 + 1) ** 0.5) + self.is_scale_input_called = True + return sample + + def get_lms_coefficient(self, order, t, current_order): + """ + Compute the linear multistep coefficient. + + Args: + order (): + t (): + current_order (): + """ + + def lms_derivative(tau): + prod = 1.0 + for k in range(order): + if current_order == k: + continue + prod *= (tau - self.sigmas[t - k]) / (self.sigmas[t - current_order] - self.sigmas[t - k]) + return prod + + integrated_coeff = integrate.quad(lms_derivative, self.sigmas[t], self.sigmas[t + 1], epsrel=1e-4)[0] + + return integrated_coeff + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + self.num_inference_steps = num_inference_steps + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = np.linspace(0, self.config.num_train_timesteps - 1, num_inference_steps, dtype=np.float32)[ + ::-1 + ].copy() + elif self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.float32) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(self.config.num_train_timesteps, 0, -step_ratio)).round().copy().astype(np.float32) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + log_sigmas = np.log(sigmas) + sigmas = np.interp(timesteps, np.arange(0, len(sigmas)), sigmas) + + if self.config.use_karras_sigmas: + sigmas = self._convert_to_karras(in_sigmas=sigmas) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + elif self.config.use_exponential_sigmas: + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + elif self.config.use_beta_sigmas: + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + + sigmas = np.concatenate([sigmas, [0.0]]).astype(np.float32) + + self.sigmas = torch.from_numpy(sigmas).to(device=device) + self.timesteps = torch.from_numpy(timesteps).to(device=device, dtype=torch.float32) + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + self.derivatives = [] + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._init_step_index + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._sigma_to_t + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + # copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_karras + def _convert_to_karras(self, in_sigmas: torch.Tensor) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + sigma_min: float = in_sigmas[-1].item() + sigma_max: float = in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, self.num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_exponential + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_beta + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + def step( + self, + model_output: torch.Tensor, + timestep: Union[float, torch.Tensor], + sample: torch.Tensor, + order: int = 4, + return_dict: bool = True, + ) -> Union[LMSDiscreteSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`float` or `torch.Tensor`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + order (`int`, defaults to 4): + The order of the linear multistep method. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_utils.SchedulerOutput`] or tuple. + + Returns: + [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_utils.SchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if not self.is_scale_input_called: + warnings.warn( + "The `scale_model_input` function should be called before `step` to ensure correct denoising. " + "See `StableDiffusionPipeline` for a usage example." + ) + + if self.step_index is None: + self._init_step_index(timestep) + + sigma = self.sigmas[self.step_index] + + # 1. compute predicted original sample (x_0) from sigma-scaled predicted noise + if self.config.prediction_type == "epsilon": + pred_original_sample = sample - sigma * model_output + elif self.config.prediction_type == "v_prediction": + # * c_out + input * c_skip + pred_original_sample = model_output * (-sigma / (sigma**2 + 1) ** 0.5) + (sample / (sigma**2 + 1)) + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, or `v_prediction`" + ) + + # 2. Convert to an ODE derivative + derivative = (sample - pred_original_sample) / sigma + self.derivatives.append(derivative) + if len(self.derivatives) > order: + self.derivatives.pop(0) + + # 3. Compute linear multistep coefficients + order = min(self.step_index + 1, order) + lms_coeffs = [self.get_lms_coefficient(order, self.step_index, curr_order) for curr_order in range(order)] + + # 4. Compute previous sample based on the derivatives path + prev_sample = sample + sum( + coeff * derivative for coeff, derivative in zip(lms_coeffs, reversed(self.derivatives)) + ) + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return ( + prev_sample, + pred_original_sample, + ) + + return LMSDiscreteSchedulerOutput(prev_sample=prev_sample, pred_original_sample=pred_original_sample) + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.Tensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # self.begin_index is None when scheduler is used for training, or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + noisy_samples = original_samples + noise * sigma + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_lms_discrete_flax.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_lms_discrete_flax.py new file mode 100644 index 0000000000000000000000000000000000000000..f1169cc90a7bd53d2ede80584e09647e5f800ccf --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_lms_discrete_flax.py @@ -0,0 +1,283 @@ +# Copyright 2024 Katherine Crowson and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import flax +import jax.numpy as jnp +from scipy import integrate + +from ..configuration_utils import ConfigMixin, register_to_config +from .scheduling_utils_flax import ( + CommonSchedulerState, + FlaxKarrasDiffusionSchedulers, + FlaxSchedulerMixin, + FlaxSchedulerOutput, + broadcast_to_shape_from_left, +) + + +@flax.struct.dataclass +class LMSDiscreteSchedulerState: + common: CommonSchedulerState + + # setable values + init_noise_sigma: jnp.ndarray + timesteps: jnp.ndarray + sigmas: jnp.ndarray + num_inference_steps: Optional[int] = None + + # running values + derivatives: Optional[jnp.ndarray] = None + + @classmethod + def create( + cls, common: CommonSchedulerState, init_noise_sigma: jnp.ndarray, timesteps: jnp.ndarray, sigmas: jnp.ndarray + ): + return cls(common=common, init_noise_sigma=init_noise_sigma, timesteps=timesteps, sigmas=sigmas) + + +@dataclass +class FlaxLMSSchedulerOutput(FlaxSchedulerOutput): + state: LMSDiscreteSchedulerState + + +class FlaxLMSDiscreteScheduler(FlaxSchedulerMixin, ConfigMixin): + """ + Linear Multistep Scheduler for discrete beta schedules. Based on the original k-diffusion implementation by + Katherine Crowson: + https://github.com/crowsonkb/k-diffusion/blob/481677d114f6ea445aa009cf5bd7a9cdee909e47/k_diffusion/sampling.py#L181 + + [`~ConfigMixin`] takes care of storing all config attributes that are passed in the scheduler's `__init__` + function, such as `num_train_timesteps`. They can be accessed via `scheduler.config.num_train_timesteps`. + [`SchedulerMixin`] provides general loading and saving functionality via the [`SchedulerMixin.save_pretrained`] and + [`~SchedulerMixin.from_pretrained`] functions. + + Args: + num_train_timesteps (`int`): number of diffusion steps used to train the model. + beta_start (`float`): the starting `beta` value of inference. + beta_end (`float`): the final `beta` value. + beta_schedule (`str`): + the beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear` or `scaled_linear`. + trained_betas (`jnp.ndarray`, optional): + option to pass an array of betas directly to the constructor to bypass `beta_start`, `beta_end` etc. + prediction_type (`str`, default `epsilon`, optional): + prediction type of the scheduler function, one of `epsilon` (predicting the noise of the diffusion + process), `sample` (directly predicting the noisy sample`) or `v_prediction` (see section 2.4 + https://imagen.research.google/video/paper.pdf) + dtype (`jnp.dtype`, *optional*, defaults to `jnp.float32`): + the `dtype` used for params and computation. + """ + + _compatibles = [e.name for e in FlaxKarrasDiffusionSchedulers] + + dtype: jnp.dtype + + @property + def has_state(self): + return True + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[jnp.ndarray] = None, + prediction_type: str = "epsilon", + dtype: jnp.dtype = jnp.float32, + ): + self.dtype = dtype + + def create_state(self, common: Optional[CommonSchedulerState] = None) -> LMSDiscreteSchedulerState: + if common is None: + common = CommonSchedulerState.create(self) + + timesteps = jnp.arange(0, self.config.num_train_timesteps).round()[::-1] + sigmas = ((1 - common.alphas_cumprod) / common.alphas_cumprod) ** 0.5 + + # standard deviation of the initial noise distribution + init_noise_sigma = sigmas.max() + + return LMSDiscreteSchedulerState.create( + common=common, + init_noise_sigma=init_noise_sigma, + timesteps=timesteps, + sigmas=sigmas, + ) + + def scale_model_input(self, state: LMSDiscreteSchedulerState, sample: jnp.ndarray, timestep: int) -> jnp.ndarray: + """ + Scales the denoising model input by `(sigma**2 + 1) ** 0.5` to match the K-LMS algorithm. + + Args: + state (`LMSDiscreteSchedulerState`): + the `FlaxLMSDiscreteScheduler` state data class instance. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + timestep (`int`): + current discrete timestep in the diffusion chain. + + Returns: + `jnp.ndarray`: scaled input sample + """ + (step_index,) = jnp.where(state.timesteps == timestep, size=1) + step_index = step_index[0] + + sigma = state.sigmas[step_index] + sample = sample / ((sigma**2 + 1) ** 0.5) + return sample + + def get_lms_coefficient(self, state: LMSDiscreteSchedulerState, order, t, current_order): + """ + Compute a linear multistep coefficient. + + Args: + order (TODO): + t (TODO): + current_order (TODO): + """ + + def lms_derivative(tau): + prod = 1.0 + for k in range(order): + if current_order == k: + continue + prod *= (tau - state.sigmas[t - k]) / (state.sigmas[t - current_order] - state.sigmas[t - k]) + return prod + + integrated_coeff = integrate.quad(lms_derivative, state.sigmas[t], state.sigmas[t + 1], epsrel=1e-4)[0] + + return integrated_coeff + + def set_timesteps( + self, state: LMSDiscreteSchedulerState, num_inference_steps: int, shape: Tuple = () + ) -> LMSDiscreteSchedulerState: + """ + Sets the timesteps used for the diffusion chain. Supporting function to be run before inference. + + Args: + state (`LMSDiscreteSchedulerState`): + the `FlaxLMSDiscreteScheduler` state data class instance. + num_inference_steps (`int`): + the number of diffusion steps used when generating samples with a pre-trained model. + """ + + timesteps = jnp.linspace(self.config.num_train_timesteps - 1, 0, num_inference_steps, dtype=self.dtype) + + low_idx = jnp.floor(timesteps).astype(jnp.int32) + high_idx = jnp.ceil(timesteps).astype(jnp.int32) + + frac = jnp.mod(timesteps, 1.0) + + sigmas = ((1 - state.common.alphas_cumprod) / state.common.alphas_cumprod) ** 0.5 + sigmas = (1 - frac) * sigmas[low_idx] + frac * sigmas[high_idx] + sigmas = jnp.concatenate([sigmas, jnp.array([0.0], dtype=self.dtype)]) + + timesteps = timesteps.astype(jnp.int32) + + # initial running values + derivatives = jnp.zeros((0,) + shape, dtype=self.dtype) + + return state.replace( + timesteps=timesteps, + sigmas=sigmas, + num_inference_steps=num_inference_steps, + derivatives=derivatives, + ) + + def step( + self, + state: LMSDiscreteSchedulerState, + model_output: jnp.ndarray, + timestep: int, + sample: jnp.ndarray, + order: int = 4, + return_dict: bool = True, + ) -> Union[FlaxLMSSchedulerOutput, Tuple]: + """ + Predict the sample at the previous timestep by reversing the SDE. Core function to propagate the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + state (`LMSDiscreteSchedulerState`): the `FlaxLMSDiscreteScheduler` state data class instance. + model_output (`jnp.ndarray`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + order: coefficient for multi-step inference. + return_dict (`bool`): option for returning tuple rather than FlaxLMSSchedulerOutput class + + Returns: + [`FlaxLMSSchedulerOutput`] or `tuple`: [`FlaxLMSSchedulerOutput`] if `return_dict` is True, otherwise a + `tuple`. When returning a tuple, the first element is the sample tensor. + + """ + if state.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + sigma = state.sigmas[timestep] + + # 1. compute predicted original sample (x_0) from sigma-scaled predicted noise + if self.config.prediction_type == "epsilon": + pred_original_sample = sample - sigma * model_output + elif self.config.prediction_type == "v_prediction": + # * c_out + input * c_skip + pred_original_sample = model_output * (-sigma / (sigma**2 + 1) ** 0.5) + (sample / (sigma**2 + 1)) + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, or `v_prediction`" + ) + + # 2. Convert to an ODE derivative + derivative = (sample - pred_original_sample) / sigma + state = state.replace(derivatives=jnp.append(state.derivatives, derivative)) + if len(state.derivatives) > order: + state = state.replace(derivatives=jnp.delete(state.derivatives, 0)) + + # 3. Compute linear multistep coefficients + order = min(timestep + 1, order) + lms_coeffs = [self.get_lms_coefficient(state, order, timestep, curr_order) for curr_order in range(order)] + + # 4. Compute previous sample based on the derivatives path + prev_sample = sample + sum( + coeff * derivative for coeff, derivative in zip(lms_coeffs, reversed(state.derivatives)) + ) + + if not return_dict: + return (prev_sample, state) + + return FlaxLMSSchedulerOutput(prev_sample=prev_sample, state=state) + + def add_noise( + self, + state: LMSDiscreteSchedulerState, + original_samples: jnp.ndarray, + noise: jnp.ndarray, + timesteps: jnp.ndarray, + ) -> jnp.ndarray: + sigma = state.sigmas[timesteps].flatten() + sigma = broadcast_to_shape_from_left(sigma, noise.shape) + + noisy_samples = original_samples + noise * sigma + + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_pndm.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_pndm.py new file mode 100644 index 0000000000000000000000000000000000000000..7a732cffc081005291d729d11d89520792efdedd --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_pndm.py @@ -0,0 +1,476 @@ +# Copyright 2024 Zhejiang University Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/ermongroup/ddim + +import math +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin, SchedulerOutput + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +class PNDMScheduler(SchedulerMixin, ConfigMixin): + """ + `PNDMScheduler` uses pseudo numerical methods for diffusion models such as the Runge-Kutta and linear multi-step + method. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + skip_prk_steps (`bool`, defaults to `False`): + Allows the scheduler to skip the Runge-Kutta steps defined in the original paper as being required before + PLMS steps. + set_alpha_to_one (`bool`, defaults to `False`): + Each diffusion step uses the alphas product value at that step and at the previous one. For the final step + there is no previous alpha. When this option is `True` the previous alpha product is fixed to `1`, + otherwise it uses the alpha value at step 0. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process) + or `v_prediction` (see section 2.4 of [Imagen Video](https://imagen.research.google/video/paper.pdf) + paper). + timestep_spacing (`str`, defaults to `"leading"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + skip_prk_steps: bool = False, + set_alpha_to_one: bool = False, + prediction_type: str = "epsilon", + timestep_spacing: str = "leading", + steps_offset: int = 0, + ): + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + self.final_alpha_cumprod = torch.tensor(1.0) if set_alpha_to_one else self.alphas_cumprod[0] + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # For now we only support F-PNDM, i.e. the runge-kutta method + # For more information on the algorithm please take a look at the paper: https://huggingface.co/papers/2202.09778 + # mainly at formula (9), (12), (13) and the Algorithm 2. + self.pndm_order = 4 + + # running values + self.cur_model_output = 0 + self.counter = 0 + self.cur_sample = None + self.ets = [] + + # setable values + self.num_inference_steps = None + self._timesteps = np.arange(0, num_train_timesteps)[::-1].copy() + self.prk_timesteps = None + self.plms_timesteps = None + self.timesteps = None + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + + self.num_inference_steps = num_inference_steps + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + self._timesteps = ( + np.linspace(0, self.config.num_train_timesteps - 1, num_inference_steps).round().astype(np.int64) + ) + elif self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + self._timesteps = (np.arange(0, num_inference_steps) * step_ratio).round() + self._timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / self.num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + self._timesteps = np.round(np.arange(self.config.num_train_timesteps, 0, -step_ratio))[::-1].astype( + np.int64 + ) + self._timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + if self.config.skip_prk_steps: + # for some models like stable diffusion the prk steps can/should be skipped to + # produce better results. When using PNDM with `self.config.skip_prk_steps` the implementation + # is based on crowsonkb's PLMS sampler implementation: https://github.com/CompVis/latent-diffusion/pull/51 + self.prk_timesteps = np.array([]) + self.plms_timesteps = np.concatenate([self._timesteps[:-1], self._timesteps[-2:-1], self._timesteps[-1:]])[ + ::-1 + ].copy() + else: + prk_timesteps = np.array(self._timesteps[-self.pndm_order :]).repeat(2) + np.tile( + np.array([0, self.config.num_train_timesteps // num_inference_steps // 2]), self.pndm_order + ) + self.prk_timesteps = (prk_timesteps[:-1].repeat(2)[1:-1])[::-1].copy() + self.plms_timesteps = self._timesteps[:-3][ + ::-1 + ].copy() # we copy to avoid having negative strides which are not supported by torch.from_numpy + + timesteps = np.concatenate([self.prk_timesteps, self.plms_timesteps]).astype(np.int64) + self.timesteps = torch.from_numpy(timesteps).to(device) + + self.ets = [] + self.counter = 0 + self.cur_model_output = 0 + + def step( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + return_dict: bool = True, + ) -> Union[SchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise), and calls [`~PNDMScheduler.step_prk`] + or [`~PNDMScheduler.step_plms`] depending on the internal variable `counter`. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_utils.SchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.counter < len(self.prk_timesteps) and not self.config.skip_prk_steps: + return self.step_prk(model_output=model_output, timestep=timestep, sample=sample, return_dict=return_dict) + else: + return self.step_plms(model_output=model_output, timestep=timestep, sample=sample, return_dict=return_dict) + + def step_prk( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + return_dict: bool = True, + ) -> Union[SchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the sample with + the Runge-Kutta method. It performs four forward passes to approximate the solution to the differential + equation. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_utils.SchedulerOutput`] or tuple. + + Returns: + [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_utils.SchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + diff_to_prev = 0 if self.counter % 2 else self.config.num_train_timesteps // self.num_inference_steps // 2 + prev_timestep = timestep - diff_to_prev + timestep = self.prk_timesteps[self.counter // 4 * 4] + + if self.counter % 4 == 0: + self.cur_model_output += 1 / 6 * model_output + self.ets.append(model_output) + self.cur_sample = sample + elif (self.counter - 1) % 4 == 0: + self.cur_model_output += 1 / 3 * model_output + elif (self.counter - 2) % 4 == 0: + self.cur_model_output += 1 / 3 * model_output + elif (self.counter - 3) % 4 == 0: + model_output = self.cur_model_output + 1 / 6 * model_output + self.cur_model_output = 0 + + # cur_sample should not be `None` + cur_sample = self.cur_sample if self.cur_sample is not None else sample + + prev_sample = self._get_prev_sample(cur_sample, timestep, prev_timestep, model_output) + self.counter += 1 + + if not return_dict: + return (prev_sample,) + + return SchedulerOutput(prev_sample=prev_sample) + + def step_plms( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + return_dict: bool = True, + ) -> Union[SchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the sample with + the linear multistep method. It performs one forward pass multiple times to approximate the solution. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_utils.SchedulerOutput`] or tuple. + + Returns: + [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_utils.SchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + if not self.config.skip_prk_steps and len(self.ets) < 3: + raise ValueError( + f"{self.__class__} can only be run AFTER scheduler has been run " + "in 'prk' mode for at least 12 iterations " + "See: https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/pipeline_pndm.py " + "for more information." + ) + + prev_timestep = timestep - self.config.num_train_timesteps // self.num_inference_steps + + if self.counter != 1: + self.ets = self.ets[-3:] + self.ets.append(model_output) + else: + prev_timestep = timestep + timestep = timestep + self.config.num_train_timesteps // self.num_inference_steps + + if len(self.ets) == 1 and self.counter == 0: + model_output = model_output + self.cur_sample = sample + elif len(self.ets) == 1 and self.counter == 1: + model_output = (model_output + self.ets[-1]) / 2 + sample = self.cur_sample + self.cur_sample = None + elif len(self.ets) == 2: + model_output = (3 * self.ets[-1] - self.ets[-2]) / 2 + elif len(self.ets) == 3: + model_output = (23 * self.ets[-1] - 16 * self.ets[-2] + 5 * self.ets[-3]) / 12 + else: + model_output = (1 / 24) * (55 * self.ets[-1] - 59 * self.ets[-2] + 37 * self.ets[-3] - 9 * self.ets[-4]) + + prev_sample = self._get_prev_sample(sample, timestep, prev_timestep, model_output) + self.counter += 1 + + if not return_dict: + return (prev_sample,) + + return SchedulerOutput(prev_sample=prev_sample) + + def scale_model_input(self, sample: torch.Tensor, *args, **kwargs) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + def _get_prev_sample(self, sample, timestep, prev_timestep, model_output): + # See formula (9) of PNDM paper https://huggingface.co/papers/2202.09778 + # this function computes x_(t−δ) using the formula of (9) + # Note that x_t needs to be added to both sides of the equation + + # Notation ( -> + # alpha_prod_t -> α_t + # alpha_prod_t_prev -> α_(t−δ) + # beta_prod_t -> (1 - α_t) + # beta_prod_t_prev -> (1 - α_(t−δ)) + # sample -> x_t + # model_output -> e_θ(x_t, t) + # prev_sample -> x_(t−δ) + alpha_prod_t = self.alphas_cumprod[timestep] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + if self.config.prediction_type == "v_prediction": + model_output = (alpha_prod_t**0.5) * model_output + (beta_prod_t**0.5) * sample + elif self.config.prediction_type != "epsilon": + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon` or `v_prediction`" + ) + + # corresponds to (α_(t−δ) - α_t) divided by + # denominator of x_t in formula (9) and plus 1 + # Note: (α_(t−δ) - α_t) / (sqrt(α_t) * (sqrt(α_(t−δ)) + sqr(α_t))) = + # sqrt(α_(t−δ)) / sqrt(α_t)) + sample_coeff = (alpha_prod_t_prev / alpha_prod_t) ** (0.5) + + # corresponds to denominator of e_θ(x_t, t) in formula (9) + model_output_denom_coeff = alpha_prod_t * beta_prod_t_prev ** (0.5) + ( + alpha_prod_t * beta_prod_t * alpha_prod_t_prev + ) ** (0.5) + + # full formula (9) + prev_sample = ( + sample_coeff * sample - (alpha_prod_t_prev - alpha_prod_t) * model_output / model_output_denom_coeff + ) + + return prev_sample + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as original_samples + # Move the self.alphas_cumprod to device to avoid redundant CPU to GPU data movement + # for the subsequent add_noise calls + self.alphas_cumprod = self.alphas_cumprod.to(device=original_samples.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=original_samples.dtype) + timesteps = timesteps.to(original_samples.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(original_samples.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(original_samples.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + noisy_samples = sqrt_alpha_prod * original_samples + sqrt_one_minus_alpha_prod * noise + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_pndm_flax.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_pndm_flax.py new file mode 100644 index 0000000000000000000000000000000000000000..59c92eae5db3862111ccfaef46c837ad8ced982c --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_pndm_flax.py @@ -0,0 +1,509 @@ +# Copyright 2024 Zhejiang University Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/ermongroup/ddim + +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import flax +import jax +import jax.numpy as jnp + +from ..configuration_utils import ConfigMixin, register_to_config +from .scheduling_utils_flax import ( + CommonSchedulerState, + FlaxKarrasDiffusionSchedulers, + FlaxSchedulerMixin, + FlaxSchedulerOutput, + add_noise_common, +) + + +@flax.struct.dataclass +class PNDMSchedulerState: + common: CommonSchedulerState + final_alpha_cumprod: jnp.ndarray + + # setable values + init_noise_sigma: jnp.ndarray + timesteps: jnp.ndarray + num_inference_steps: Optional[int] = None + prk_timesteps: Optional[jnp.ndarray] = None + plms_timesteps: Optional[jnp.ndarray] = None + + # running values + cur_model_output: Optional[jnp.ndarray] = None + counter: Optional[jnp.int32] = None + cur_sample: Optional[jnp.ndarray] = None + ets: Optional[jnp.ndarray] = None + + @classmethod + def create( + cls, + common: CommonSchedulerState, + final_alpha_cumprod: jnp.ndarray, + init_noise_sigma: jnp.ndarray, + timesteps: jnp.ndarray, + ): + return cls( + common=common, + final_alpha_cumprod=final_alpha_cumprod, + init_noise_sigma=init_noise_sigma, + timesteps=timesteps, + ) + + +@dataclass +class FlaxPNDMSchedulerOutput(FlaxSchedulerOutput): + state: PNDMSchedulerState + + +class FlaxPNDMScheduler(FlaxSchedulerMixin, ConfigMixin): + """ + Pseudo numerical methods for diffusion models (PNDM) proposes using more advanced ODE integration techniques, + namely Runge-Kutta method and a linear multi-step method. + + [`~ConfigMixin`] takes care of storing all config attributes that are passed in the scheduler's `__init__` + function, such as `num_train_timesteps`. They can be accessed via `scheduler.config.num_train_timesteps`. + [`SchedulerMixin`] provides general loading and saving functionality via the [`SchedulerMixin.save_pretrained`] and + [`~SchedulerMixin.from_pretrained`] functions. + + For more details, see the original paper: https://huggingface.co/papers/2202.09778 + + Args: + num_train_timesteps (`int`): number of diffusion steps used to train the model. + beta_start (`float`): the starting `beta` value of inference. + beta_end (`float`): the final `beta` value. + beta_schedule (`str`): + the beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`jnp.ndarray`, optional): + option to pass an array of betas directly to the constructor to bypass `beta_start`, `beta_end` etc. + skip_prk_steps (`bool`): + allows the scheduler to skip the Runge-Kutta steps that are defined in the original paper as being required + before plms steps; defaults to `False`. + set_alpha_to_one (`bool`, default `False`): + each diffusion step uses the value of alphas product at that step and at the previous one. For the final + step there is no previous alpha. When this option is `True` the previous alpha product is fixed to `1`, + otherwise it uses the value of alpha at step 0. + steps_offset (`int`, default `0`): + An offset added to the inference steps, as required by some model families. + prediction_type (`str`, default `epsilon`, optional): + prediction type of the scheduler function, one of `epsilon` (predicting the noise of the diffusion + process), `sample` (directly predicting the noisy sample`) or `v_prediction` (see section 2.4 + https://imagen.research.google/video/paper.pdf) + dtype (`jnp.dtype`, *optional*, defaults to `jnp.float32`): + the `dtype` used for params and computation. + """ + + _compatibles = [e.name for e in FlaxKarrasDiffusionSchedulers] + + dtype: jnp.dtype + pndm_order: int + + @property + def has_state(self): + return True + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[jnp.ndarray] = None, + skip_prk_steps: bool = False, + set_alpha_to_one: bool = False, + steps_offset: int = 0, + prediction_type: str = "epsilon", + dtype: jnp.dtype = jnp.float32, + ): + self.dtype = dtype + + # For now we only support F-PNDM, i.e. the runge-kutta method + # For more information on the algorithm please take a look at the paper: https://huggingface.co/papers/2202.09778 + # mainly at formula (9), (12), (13) and the Algorithm 2. + self.pndm_order = 4 + + def create_state(self, common: Optional[CommonSchedulerState] = None) -> PNDMSchedulerState: + if common is None: + common = CommonSchedulerState.create(self) + + # At every step in ddim, we are looking into the previous alphas_cumprod + # For the final step, there is no previous alphas_cumprod because we are already at 0 + # `set_alpha_to_one` decides whether we set this parameter simply to one or + # whether we use the final alpha of the "non-previous" one. + final_alpha_cumprod = ( + jnp.array(1.0, dtype=self.dtype) if self.config.set_alpha_to_one else common.alphas_cumprod[0] + ) + + # standard deviation of the initial noise distribution + init_noise_sigma = jnp.array(1.0, dtype=self.dtype) + + timesteps = jnp.arange(0, self.config.num_train_timesteps).round()[::-1] + + return PNDMSchedulerState.create( + common=common, + final_alpha_cumprod=final_alpha_cumprod, + init_noise_sigma=init_noise_sigma, + timesteps=timesteps, + ) + + def set_timesteps(self, state: PNDMSchedulerState, num_inference_steps: int, shape: Tuple) -> PNDMSchedulerState: + """ + Sets the discrete timesteps used for the diffusion chain. Supporting function to be run before inference. + + Args: + state (`PNDMSchedulerState`): + the `FlaxPNDMScheduler` state data class instance. + num_inference_steps (`int`): + the number of diffusion steps used when generating samples with a pre-trained model. + shape (`Tuple`): + the shape of the samples to be generated. + """ + + step_ratio = self.config.num_train_timesteps // num_inference_steps + # creates integer timesteps by multiplying by ratio + # rounding to avoid issues when num_inference_step is power of 3 + _timesteps = (jnp.arange(0, num_inference_steps) * step_ratio).round() + self.config.steps_offset + + if self.config.skip_prk_steps: + # for some models like stable diffusion the prk steps can/should be skipped to + # produce better results. When using PNDM with `self.config.skip_prk_steps` the implementation + # is based on crowsonkb's PLMS sampler implementation: https://github.com/CompVis/latent-diffusion/pull/51 + + prk_timesteps = jnp.array([], dtype=jnp.int32) + plms_timesteps = jnp.concatenate([_timesteps[:-1], _timesteps[-2:-1], _timesteps[-1:]])[::-1] + + else: + prk_timesteps = _timesteps[-self.pndm_order :].repeat(2) + jnp.tile( + jnp.array([0, self.config.num_train_timesteps // num_inference_steps // 2], dtype=jnp.int32), + self.pndm_order, + ) + + prk_timesteps = (prk_timesteps[:-1].repeat(2)[1:-1])[::-1] + plms_timesteps = _timesteps[:-3][::-1] + + timesteps = jnp.concatenate([prk_timesteps, plms_timesteps]) + + # initial running values + + cur_model_output = jnp.zeros(shape, dtype=self.dtype) + counter = jnp.int32(0) + cur_sample = jnp.zeros(shape, dtype=self.dtype) + ets = jnp.zeros((4,) + shape, dtype=self.dtype) + + return state.replace( + timesteps=timesteps, + num_inference_steps=num_inference_steps, + prk_timesteps=prk_timesteps, + plms_timesteps=plms_timesteps, + cur_model_output=cur_model_output, + counter=counter, + cur_sample=cur_sample, + ets=ets, + ) + + def scale_model_input( + self, state: PNDMSchedulerState, sample: jnp.ndarray, timestep: Optional[int] = None + ) -> jnp.ndarray: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + state (`PNDMSchedulerState`): the `FlaxPNDMScheduler` state data class instance. + sample (`jnp.ndarray`): input sample + timestep (`int`, optional): current timestep + + Returns: + `jnp.ndarray`: scaled input sample + """ + return sample + + def step( + self, + state: PNDMSchedulerState, + model_output: jnp.ndarray, + timestep: int, + sample: jnp.ndarray, + return_dict: bool = True, + ) -> Union[FlaxPNDMSchedulerOutput, Tuple]: + """ + Predict the sample at the previous timestep by reversing the SDE. Core function to propagate the diffusion + process from the learned model outputs (most often the predicted noise). + + This function calls `step_prk()` or `step_plms()` depending on the internal variable `counter`. + + Args: + state (`PNDMSchedulerState`): the `FlaxPNDMScheduler` state data class instance. + model_output (`jnp.ndarray`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + return_dict (`bool`): option for returning tuple rather than FlaxPNDMSchedulerOutput class + + Returns: + [`FlaxPNDMSchedulerOutput`] or `tuple`: [`FlaxPNDMSchedulerOutput`] if `return_dict` is True, otherwise a + `tuple`. When returning a tuple, the first element is the sample tensor. + + """ + + if state.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + if self.config.skip_prk_steps: + prev_sample, state = self.step_plms(state, model_output, timestep, sample) + else: + prk_prev_sample, prk_state = self.step_prk(state, model_output, timestep, sample) + plms_prev_sample, plms_state = self.step_plms(state, model_output, timestep, sample) + + cond = state.counter < len(state.prk_timesteps) + + prev_sample = jax.lax.select(cond, prk_prev_sample, plms_prev_sample) + + state = state.replace( + cur_model_output=jax.lax.select(cond, prk_state.cur_model_output, plms_state.cur_model_output), + ets=jax.lax.select(cond, prk_state.ets, plms_state.ets), + cur_sample=jax.lax.select(cond, prk_state.cur_sample, plms_state.cur_sample), + counter=jax.lax.select(cond, prk_state.counter, plms_state.counter), + ) + + if not return_dict: + return (prev_sample, state) + + return FlaxPNDMSchedulerOutput(prev_sample=prev_sample, state=state) + + def step_prk( + self, + state: PNDMSchedulerState, + model_output: jnp.ndarray, + timestep: int, + sample: jnp.ndarray, + ) -> Union[FlaxPNDMSchedulerOutput, Tuple]: + """ + Step function propagating the sample with the Runge-Kutta method. RK takes 4 forward passes to approximate the + solution to the differential equation. + + Args: + state (`PNDMSchedulerState`): the `FlaxPNDMScheduler` state data class instance. + model_output (`jnp.ndarray`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + return_dict (`bool`): option for returning tuple rather than FlaxPNDMSchedulerOutput class + + Returns: + [`FlaxPNDMSchedulerOutput`] or `tuple`: [`FlaxPNDMSchedulerOutput`] if `return_dict` is True, otherwise a + `tuple`. When returning a tuple, the first element is the sample tensor. + + """ + + if state.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + diff_to_prev = jnp.where( + state.counter % 2, 0, self.config.num_train_timesteps // state.num_inference_steps // 2 + ) + prev_timestep = timestep - diff_to_prev + timestep = state.prk_timesteps[state.counter // 4 * 4] + + model_output = jax.lax.select( + (state.counter % 4) != 3, + model_output, # remainder 0, 1, 2 + state.cur_model_output + 1 / 6 * model_output, # remainder 3 + ) + + state = state.replace( + cur_model_output=jax.lax.select_n( + state.counter % 4, + state.cur_model_output + 1 / 6 * model_output, # remainder 0 + state.cur_model_output + 1 / 3 * model_output, # remainder 1 + state.cur_model_output + 1 / 3 * model_output, # remainder 2 + jnp.zeros_like(state.cur_model_output), # remainder 3 + ), + ets=jax.lax.select( + (state.counter % 4) == 0, + state.ets.at[0:3].set(state.ets[1:4]).at[3].set(model_output), # remainder 0 + state.ets, # remainder 1, 2, 3 + ), + cur_sample=jax.lax.select( + (state.counter % 4) == 0, + sample, # remainder 0 + state.cur_sample, # remainder 1, 2, 3 + ), + ) + + cur_sample = state.cur_sample + prev_sample = self._get_prev_sample(state, cur_sample, timestep, prev_timestep, model_output) + state = state.replace(counter=state.counter + 1) + + return (prev_sample, state) + + def step_plms( + self, + state: PNDMSchedulerState, + model_output: jnp.ndarray, + timestep: int, + sample: jnp.ndarray, + ) -> Union[FlaxPNDMSchedulerOutput, Tuple]: + """ + Step function propagating the sample with the linear multi-step method. This has one forward pass with multiple + times to approximate the solution. + + Args: + state (`PNDMSchedulerState`): the `FlaxPNDMScheduler` state data class instance. + model_output (`jnp.ndarray`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + return_dict (`bool`): option for returning tuple rather than FlaxPNDMSchedulerOutput class + + Returns: + [`FlaxPNDMSchedulerOutput`] or `tuple`: [`FlaxPNDMSchedulerOutput`] if `return_dict` is True, otherwise a + `tuple`. When returning a tuple, the first element is the sample tensor. + + """ + + if state.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + # NOTE: There is no way to check in the jitted runtime if the prk mode was ran before + + prev_timestep = timestep - self.config.num_train_timesteps // state.num_inference_steps + prev_timestep = jnp.where(prev_timestep > 0, prev_timestep, 0) + + # Reference: + # if state.counter != 1: + # state.ets.append(model_output) + # else: + # prev_timestep = timestep + # timestep = timestep + self.config.num_train_timesteps // state.num_inference_steps + + prev_timestep = jnp.where(state.counter == 1, timestep, prev_timestep) + timestep = jnp.where( + state.counter == 1, timestep + self.config.num_train_timesteps // state.num_inference_steps, timestep + ) + + # Reference: + # if len(state.ets) == 1 and state.counter == 0: + # model_output = model_output + # state.cur_sample = sample + # elif len(state.ets) == 1 and state.counter == 1: + # model_output = (model_output + state.ets[-1]) / 2 + # sample = state.cur_sample + # state.cur_sample = None + # elif len(state.ets) == 2: + # model_output = (3 * state.ets[-1] - state.ets[-2]) / 2 + # elif len(state.ets) == 3: + # model_output = (23 * state.ets[-1] - 16 * state.ets[-2] + 5 * state.ets[-3]) / 12 + # else: + # model_output = (1 / 24) * (55 * state.ets[-1] - 59 * state.ets[-2] + 37 * state.ets[-3] - 9 * state.ets[-4]) + + state = state.replace( + ets=jax.lax.select( + state.counter != 1, + state.ets.at[0:3].set(state.ets[1:4]).at[3].set(model_output), # counter != 1 + state.ets, # counter 1 + ), + cur_sample=jax.lax.select( + state.counter != 1, + sample, # counter != 1 + state.cur_sample, # counter 1 + ), + ) + + state = state.replace( + cur_model_output=jax.lax.select_n( + jnp.clip(state.counter, 0, 4), + model_output, # counter 0 + (model_output + state.ets[-1]) / 2, # counter 1 + (3 * state.ets[-1] - state.ets[-2]) / 2, # counter 2 + (23 * state.ets[-1] - 16 * state.ets[-2] + 5 * state.ets[-3]) / 12, # counter 3 + (1 / 24) + * (55 * state.ets[-1] - 59 * state.ets[-2] + 37 * state.ets[-3] - 9 * state.ets[-4]), # counter >= 4 + ), + ) + + sample = state.cur_sample + model_output = state.cur_model_output + prev_sample = self._get_prev_sample(state, sample, timestep, prev_timestep, model_output) + state = state.replace(counter=state.counter + 1) + + return (prev_sample, state) + + def _get_prev_sample(self, state: PNDMSchedulerState, sample, timestep, prev_timestep, model_output): + # See formula (9) of PNDM paper https://huggingface.co/papers/2202.09778 + # this function computes x_(t−δ) using the formula of (9) + # Note that x_t needs to be added to both sides of the equation + + # Notation ( -> + # alpha_prod_t -> α_t + # alpha_prod_t_prev -> α_(t−δ) + # beta_prod_t -> (1 - α_t) + # beta_prod_t_prev -> (1 - α_(t−δ)) + # sample -> x_t + # model_output -> e_θ(x_t, t) + # prev_sample -> x_(t−δ) + alpha_prod_t = state.common.alphas_cumprod[timestep] + alpha_prod_t_prev = jnp.where( + prev_timestep >= 0, state.common.alphas_cumprod[prev_timestep], state.final_alpha_cumprod + ) + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + if self.config.prediction_type == "v_prediction": + model_output = (alpha_prod_t**0.5) * model_output + (beta_prod_t**0.5) * sample + elif self.config.prediction_type != "epsilon": + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon` or `v_prediction`" + ) + + # corresponds to (α_(t−δ) - α_t) divided by + # denominator of x_t in formula (9) and plus 1 + # Note: (α_(t−δ) - α_t) / (sqrt(α_t) * (sqrt(α_(t−δ)) + sqr(α_t))) = + # sqrt(α_(t−δ)) / sqrt(α_t)) + sample_coeff = (alpha_prod_t_prev / alpha_prod_t) ** (0.5) + + # corresponds to denominator of e_θ(x_t, t) in formula (9) + model_output_denom_coeff = alpha_prod_t * beta_prod_t_prev ** (0.5) + ( + alpha_prod_t * beta_prod_t * alpha_prod_t_prev + ) ** (0.5) + + # full formula (9) + prev_sample = ( + sample_coeff * sample - (alpha_prod_t_prev - alpha_prod_t) * model_output / model_output_denom_coeff + ) + + return prev_sample + + def add_noise( + self, + state: PNDMSchedulerState, + original_samples: jnp.ndarray, + noise: jnp.ndarray, + timesteps: jnp.ndarray, + ) -> jnp.ndarray: + return add_noise_common(state.common, original_samples, noise, timesteps) + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_repaint.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_repaint.py new file mode 100644 index 0000000000000000000000000000000000000000..7dae0337faa4f40c9f9b31aad44e4ee714ff5951 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_repaint.py @@ -0,0 +1,365 @@ +# Copyright 2024 ETH Zurich Computer Vision Lab and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import SchedulerMixin + + +@dataclass +class RePaintSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's step function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample (x_{t-1}) of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample (x_{0}) based on the model output from + the current timestep. `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: torch.Tensor + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +class RePaintScheduler(SchedulerMixin, ConfigMixin): + """ + `RePaintScheduler` is a scheduler for DDPM inpainting inside a given mask. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, `squaredcos_cap_v2`, or `sigmoid`. + eta (`float`): + The weight of noise for added noise in diffusion step. If its value is between 0.0 and 1.0 it corresponds + to the DDIM scheduler, and if its value is between -0.0 and 1.0 it corresponds to the DDPM scheduler. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + clip_sample (`bool`, defaults to `True`): + Clip the predicted sample between -1 and 1 for numerical stability. + + """ + + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + eta: float = 0.0, + trained_betas: Optional[np.ndarray] = None, + clip_sample: bool = True, + ): + if trained_betas is not None: + self.betas = torch.from_numpy(trained_betas) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + elif beta_schedule == "sigmoid": + # GeoDiff sigmoid schedule + betas = torch.linspace(-6, 6, num_train_timesteps) + self.betas = torch.sigmoid(betas) * (beta_end - beta_start) + beta_start + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + self.one = torch.tensor(1.0) + + self.final_alpha_cumprod = torch.tensor(1.0) + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # setable values + self.num_inference_steps = None + self.timesteps = torch.from_numpy(np.arange(0, num_train_timesteps)[::-1].copy()) + + self.eta = eta + + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + def set_timesteps( + self, + num_inference_steps: int, + jump_length: int = 10, + jump_n_sample: int = 10, + device: Union[str, torch.device] = None, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. If used, + `timesteps` must be `None`. + jump_length (`int`, defaults to 10): + The number of steps taken forward in time before going backward in time for a single jump (“j” in + RePaint paper). Take a look at Figure 9 and 10 in the paper. + jump_n_sample (`int`, defaults to 10): + The number of times to make a forward time jump for a given chosen time sample. Take a look at Figure 9 + and 10 in the paper. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + + """ + num_inference_steps = min(self.config.num_train_timesteps, num_inference_steps) + self.num_inference_steps = num_inference_steps + + timesteps = [] + + jumps = {} + for j in range(0, num_inference_steps - jump_length, jump_length): + jumps[j] = jump_n_sample - 1 + + t = num_inference_steps + while t >= 1: + t = t - 1 + timesteps.append(t) + + if jumps.get(t, 0) > 0: + jumps[t] = jumps[t] - 1 + for _ in range(jump_length): + t = t + 1 + timesteps.append(t) + + timesteps = np.array(timesteps) * (self.config.num_train_timesteps // self.num_inference_steps) + self.timesteps = torch.from_numpy(timesteps).to(device) + + def _get_variance(self, t): + prev_timestep = t - self.config.num_train_timesteps // self.num_inference_steps + + alpha_prod_t = self.alphas_cumprod[t] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + # For t > 0, compute predicted variance βt (see formula (6) and (7) from + # https://huggingface.co/papers/2006.11239) and sample from it to get + # previous sample x_{t-1} ~ N(pred_prev_sample, variance) == add + # variance to pred_sample + # Is equivalent to formula (16) in https://huggingface.co/papers/2010.02502 + # without eta. + # variance = (1 - alpha_prod_t_prev) / (1 - alpha_prod_t) * self.betas[t] + variance = (beta_prod_t_prev / beta_prod_t) * (1 - alpha_prod_t / alpha_prod_t_prev) + + return variance + + def step( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + original_image: torch.Tensor, + mask: torch.Tensor, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[RePaintSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + original_image (`torch.Tensor`): + The original image to inpaint on. + mask (`torch.Tensor`): + The mask where a value of 0.0 indicates which part of the original image to inpaint. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_repaint.RePaintSchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_repaint.RePaintSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_repaint.RePaintSchedulerOutput`] is returned, + otherwise a tuple is returned where the first element is the sample tensor. + + """ + t = timestep + prev_timestep = timestep - self.config.num_train_timesteps // self.num_inference_steps + + # 1. compute alphas, betas + alpha_prod_t = self.alphas_cumprod[t] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + beta_prod_t = 1 - alpha_prod_t + + # 2. compute predicted original sample from predicted noise also called + # "predicted x_0" of formula (15) from https://huggingface.co/papers/2006.11239 + pred_original_sample = (sample - beta_prod_t**0.5 * model_output) / alpha_prod_t**0.5 + + # 3. Clip "predicted x_0" + if self.config.clip_sample: + pred_original_sample = torch.clamp(pred_original_sample, -1, 1) + + # We choose to follow RePaint Algorithm 1 to get x_{t-1}, however we + # substitute formula (7) in the algorithm coming from DDPM paper + # (formula (4) Algorithm 2 - Sampling) with formula (12) from DDIM paper. + # DDIM schedule gives the same results as DDPM with eta = 1.0 + # Noise is being reused in 7. and 8., but no impact on quality has + # been observed. + + # 5. Add noise + device = model_output.device + noise = randn_tensor(model_output.shape, generator=generator, device=device, dtype=model_output.dtype) + std_dev_t = self.eta * self._get_variance(timestep) ** 0.5 + + variance = 0 + if t > 0 and self.eta > 0: + variance = std_dev_t * noise + + # 6. compute "direction pointing to x_t" of formula (12) + # from https://huggingface.co/papers/2010.02502 + pred_sample_direction = (1 - alpha_prod_t_prev - std_dev_t**2) ** 0.5 * model_output + + # 7. compute x_{t-1} of formula (12) from https://huggingface.co/papers/2010.02502 + prev_unknown_part = alpha_prod_t_prev**0.5 * pred_original_sample + pred_sample_direction + variance + + # 8. Algorithm 1 Line 5 https://huggingface.co/papers/2201.09865 + # The computation reported in Algorithm 1 Line 5 is incorrect. Line 5 refers to formula (8a) of the same paper, + # which tells to sample from a Gaussian distribution with mean "(alpha_prod_t_prev**0.5) * original_image" + # and variance "(1 - alpha_prod_t_prev)". This means that the standard Gaussian distribution "noise" should be + # scaled by the square root of the variance (as it is done here), however Algorithm 1 Line 5 tells to scale by the variance. + prev_known_part = (alpha_prod_t_prev**0.5) * original_image + ((1 - alpha_prod_t_prev) ** 0.5) * noise + + # 9. Algorithm 1 Line 8 https://huggingface.co/papers/2201.09865 + pred_prev_sample = mask * prev_known_part + (1.0 - mask) * prev_unknown_part + + if not return_dict: + return ( + pred_prev_sample, + pred_original_sample, + ) + + return RePaintSchedulerOutput(prev_sample=pred_prev_sample, pred_original_sample=pred_original_sample) + + def undo_step(self, sample, timestep, generator=None): + n = self.config.num_train_timesteps // self.num_inference_steps + + for i in range(n): + beta = self.betas[timestep + i] + if sample.device.type == "mps": + # randn does not work reproducibly on mps + noise = randn_tensor(sample.shape, dtype=sample.dtype, generator=generator) + noise = noise.to(sample.device) + else: + noise = randn_tensor(sample.shape, generator=generator, device=sample.device, dtype=sample.dtype) + + # 10. Algorithm 1 Line 10 https://huggingface.co/papers/2201.09865 + sample = (1 - beta) ** 0.5 * sample + beta**0.5 * noise + + return sample + + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + raise NotImplementedError("Use `DDPMScheduler.add_noise()` to train for sampling with RePaint.") + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_sasolver.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_sasolver.py new file mode 100644 index 0000000000000000000000000000000000000000..6a48859a4488f372cf0918a0bb2f3d38ce10d74d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_sasolver.py @@ -0,0 +1,1221 @@ +# Copyright 2024 Shuchen Xue, etc. in University of Chinese Academy of Sciences Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: check https://huggingface.co/papers/2309.05019 +# The codebase is modified based on https://github.com/huggingface/diffusers/blob/main/src/diffusers/schedulers/scheduling_dpmsolver_multistep.py + +import math +from typing import Callable, List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import deprecate, is_scipy_available +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin, SchedulerOutput + + +if is_scipy_available(): + import scipy.stats + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +class SASolverScheduler(SchedulerMixin, ConfigMixin): + """ + `SASolverScheduler` is a fast dedicated high-order solver for diffusion SDEs. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + predictor_order (`int`, defaults to 2): + The predictor order which can be `1` or `2` or `3` or '4'. It is recommended to use `predictor_order=2` for + guided sampling, and `predictor_order=3` for unconditional sampling. + corrector_order (`int`, defaults to 2): + The corrector order which can be `1` or `2` or `3` or '4'. It is recommended to use `corrector_order=2` for + guided sampling, and `corrector_order=3` for unconditional sampling. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + tau_func (`Callable`, *optional*): + Stochasticity during the sampling. Default in init is `lambda t: 1 if t >= 200 and t <= 800 else 0`. + SA-Solver will sample from vanilla diffusion ODE if tau_func is set to `lambda t: 0`. SA-Solver will sample + from vanilla diffusion SDE if tau_func is set to `lambda t: 1`. For more details, please check + https://huggingface.co/papers/2309.05019 + thresholding (`bool`, defaults to `False`): + Whether to use the "dynamic thresholding" method. This is unsuitable for latent-space diffusion models such + as Stable Diffusion. + dynamic_thresholding_ratio (`float`, defaults to 0.995): + The ratio for the dynamic thresholding method. Valid only when `thresholding=True`. + sample_max_value (`float`, defaults to 1.0): + The threshold value for dynamic thresholding. Valid only when `thresholding=True` and + `algorithm_type="dpmsolver++"`. + algorithm_type (`str`, defaults to `data_prediction`): + Algorithm type for the solver; can be `data_prediction` or `noise_prediction`. It is recommended to use + `data_prediction` with `solver_order=2` for guided sampling like in Stable Diffusion. + lower_order_final (`bool`, defaults to `True`): + Whether to use lower-order solvers in the final steps. Default = True. + use_karras_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use Karras sigmas for step sizes in the noise schedule during the sampling process. If `True`, + the sigmas are determined according to a sequence of noise levels {σi}. + use_exponential_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use exponential sigmas for step sizes in the noise schedule during the sampling process. + use_beta_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use beta sigmas for step sizes in the noise schedule during the sampling process. Refer to [Beta + Sampling is All You Need](https://huggingface.co/papers/2407.12173) for more information. + lambda_min_clipped (`float`, defaults to `-inf`): + Clipping threshold for the minimum value of `lambda(t)` for numerical stability. This is critical for the + cosine (`squaredcos_cap_v2`) noise schedule. + variance_type (`str`, *optional*): + Set to "learned" or "learned_range" for diffusion models that predict variance. If set, the model's output + contains the predicted Gaussian variance. + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + predictor_order: int = 2, + corrector_order: int = 2, + prediction_type: str = "epsilon", + tau_func: Optional[Callable] = None, + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + sample_max_value: float = 1.0, + algorithm_type: str = "data_prediction", + lower_order_final: bool = True, + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + use_flow_sigmas: Optional[bool] = False, + flow_shift: Optional[float] = 1.0, + lambda_min_clipped: float = -float("inf"), + variance_type: Optional[str] = None, + timestep_spacing: str = "linspace", + steps_offset: int = 0, + ): + if self.config.use_beta_sigmas and not is_scipy_available(): + raise ImportError("Make sure to install scipy if you want to use beta sigmas.") + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = ( + torch.linspace( + beta_start**0.5, + beta_end**0.5, + num_train_timesteps, + dtype=torch.float32, + ) + ** 2 + ) + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + # Currently we only support VP-type noise schedule + self.alpha_t = torch.sqrt(self.alphas_cumprod) + self.sigma_t = torch.sqrt(1 - self.alphas_cumprod) + self.lambda_t = torch.log(self.alpha_t) - torch.log(self.sigma_t) + self.sigmas = ((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5 + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + if algorithm_type not in ["data_prediction", "noise_prediction"]: + raise NotImplementedError(f"{algorithm_type} is not implemented for {self.__class__}") + + # setable values + self.num_inference_steps = None + timesteps = np.linspace(0, num_train_timesteps - 1, num_train_timesteps, dtype=np.float32)[::-1].copy() + self.timesteps = torch.from_numpy(timesteps) + self.timestep_list = [None] * max(predictor_order, corrector_order - 1) + self.model_outputs = [None] * max(predictor_order, corrector_order - 1) + + if tau_func is None: + self.tau_func = lambda t: 1 if t >= 200 and t <= 800 else 0 + else: + self.tau_func = tau_func + self.predict_x0 = algorithm_type == "data_prediction" + self.lower_order_nums = 0 + self.last_sample = None + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def set_timesteps(self, num_inference_steps: int = None, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + # Clipping the minimum of all lambda(t) for numerical stability. + # This is critical for cosine (squaredcos_cap_v2) noise schedule. + clipped_idx = torch.searchsorted(torch.flip(self.lambda_t, [0]), self.config.lambda_min_clipped) + last_timestep = ((self.config.num_train_timesteps - clipped_idx).numpy()).item() + + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = ( + np.linspace(0, last_timestep - 1, num_inference_steps + 1).round()[::-1][:-1].copy().astype(np.int64) + ) + + elif self.config.timestep_spacing == "leading": + step_ratio = last_timestep // (num_inference_steps + 1) + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps + 1) * step_ratio).round()[::-1][:-1].copy().astype(np.int64) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = np.arange(last_timestep, 0, -step_ratio).round().copy().astype(np.int64) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + log_sigmas = np.log(sigmas) + if self.config.use_karras_sigmas: + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_karras(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]).round() + sigmas = np.concatenate([sigmas, sigmas[-1:]]).astype(np.float32) + elif self.config.use_exponential_sigmas: + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + sigmas = np.concatenate([sigmas, sigmas[-1:]]).astype(np.float32) + elif self.config.use_beta_sigmas: + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + sigmas = np.concatenate([sigmas, sigmas[-1:]]).astype(np.float32) + elif self.config.use_flow_sigmas: + alphas = np.linspace(1, 1 / self.config.num_train_timesteps, num_inference_steps + 1) + sigmas = 1.0 - alphas + sigmas = np.flip(self.config.flow_shift * sigmas / (1 + (self.config.flow_shift - 1) * sigmas))[:-1].copy() + timesteps = (sigmas * self.config.num_train_timesteps).copy() + sigmas = np.concatenate([sigmas, sigmas[-1:]]).astype(np.float32) + else: + sigmas = np.interp(timesteps, np.arange(0, len(sigmas)), sigmas) + sigma_last = ((1 - self.alphas_cumprod[0]) / self.alphas_cumprod[0]) ** 0.5 + sigmas = np.concatenate([sigmas, [sigma_last]]).astype(np.float32) + + self.sigmas = torch.from_numpy(sigmas) + self.timesteps = torch.from_numpy(timesteps).to(device=device, dtype=torch.int64) + + self.num_inference_steps = len(timesteps) + self.model_outputs = [ + None, + ] * max(self.config.predictor_order, self.config.corrector_order - 1) + self.lower_order_nums = 0 + self.last_sample = None + + # add an index counter for schedulers that allow duplicated timesteps + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler._threshold_sample + def _threshold_sample(self, sample: torch.Tensor) -> torch.Tensor: + """ + "Dynamic thresholding: At each sampling step we set s to a certain percentile absolute pixel value in xt0 (the + prediction of x_0 at timestep t), and if s > 1, then we threshold xt0 to the range [-s, s] and then divide by + s. Dynamic thresholding pushes saturated pixels (those near -1 and 1) inwards, thereby actively preventing + pixels from saturation at each step. We find that dynamic thresholding results in significantly better + photorealism as well as better image-text alignment, especially when using very large guidance weights." + + https://huggingface.co/papers/2205.11487 + """ + dtype = sample.dtype + batch_size, channels, *remaining_dims = sample.shape + + if dtype not in (torch.float32, torch.float64): + sample = sample.float() # upcast for quantile calculation, and clamp not implemented for cpu half + + # Flatten sample for doing quantile calculation along each image + sample = sample.reshape(batch_size, channels * np.prod(remaining_dims)) + + abs_sample = sample.abs() # "a certain percentile absolute pixel value" + + s = torch.quantile(abs_sample, self.config.dynamic_thresholding_ratio, dim=1) + s = torch.clamp( + s, min=1, max=self.config.sample_max_value + ) # When clamped to min=1, equivalent to standard clipping to [-1, 1] + s = s.unsqueeze(1) # (batch_size, 1) because clamp will broadcast along dim=0 + sample = torch.clamp(sample, -s, s) / s # "we threshold xt0 to the range [-s, s] and then divide by s" + + sample = sample.reshape(batch_size, channels, *remaining_dims) + sample = sample.to(dtype) + + return sample + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._sigma_to_t + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler._sigma_to_alpha_sigma_t + def _sigma_to_alpha_sigma_t(self, sigma): + if self.config.use_flow_sigmas: + alpha_t = 1 - sigma + sigma_t = sigma + else: + alpha_t = 1 / ((sigma**2 + 1) ** 0.5) + sigma_t = sigma * alpha_t + + return alpha_t, sigma_t + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_karras + def _convert_to_karras(self, in_sigmas: torch.Tensor, num_inference_steps) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_exponential + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_beta + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + def convert_model_output( + self, + model_output: torch.Tensor, + *args, + sample: torch.Tensor = None, + **kwargs, + ) -> torch.Tensor: + """ + Convert the model output to the corresponding type the data_prediction/noise_prediction algorithm needs. + Noise_prediction is designed to discretize an integral of the noise prediction model, and data_prediction is + designed to discretize an integral of the data prediction model. + + + + The algorithm and model type are decoupled. You can use either data_prediction or noise_prediction for both + noise prediction and data prediction models. + + + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The converted model output. + """ + timestep = args[0] if len(args) > 0 else kwargs.pop("timestep", None) + if sample is None: + if len(args) > 1: + sample = args[1] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep is not None: + deprecate( + "timesteps", + "1.0.0", + "Passing `timesteps` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + # SA-Solver_data_prediction needs to solve an integral of the data prediction model. + if self.config.algorithm_type in ["data_prediction"]: + if self.config.prediction_type == "epsilon": + # SA-Solver only needs the "mean" output. + if self.config.variance_type in ["learned", "learned_range"]: + model_output = model_output[:, :3] + x0_pred = (sample - sigma_t * model_output) / alpha_t + elif self.config.prediction_type == "sample": + x0_pred = model_output + elif self.config.prediction_type == "v_prediction": + x0_pred = alpha_t * sample - sigma_t * model_output + elif self.config.prediction_type == "flow_prediction": + sigma_t = self.sigmas[self.step_index] + x0_pred = sample - sigma_t * model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, " + "`v_prediction`, or `flow_prediction` for the SASolverScheduler." + ) + + if self.config.thresholding: + x0_pred = self._threshold_sample(x0_pred) + + return x0_pred + + # SA-Solver_noise_prediction needs to solve an integral of the noise prediction model. + elif self.config.algorithm_type in ["noise_prediction"]: + if self.config.prediction_type == "epsilon": + # SA-Solver only needs the "mean" output. + if self.config.variance_type in ["learned", "learned_range"]: + epsilon = model_output[:, :3] + else: + epsilon = model_output + elif self.config.prediction_type == "sample": + epsilon = (sample - alpha_t * model_output) / sigma_t + elif self.config.prediction_type == "v_prediction": + epsilon = alpha_t * model_output + sigma_t * sample + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, or" + " `v_prediction` for the SASolverScheduler." + ) + + if self.config.thresholding: + alpha_t, sigma_t = self.alpha_t[timestep], self.sigma_t[timestep] + x0_pred = (sample - sigma_t * epsilon) / alpha_t + x0_pred = self._threshold_sample(x0_pred) + epsilon = (sample - alpha_t * x0_pred) / sigma_t + + return epsilon + + def get_coefficients_exponential_negative(self, order, interval_start, interval_end): + """ + Calculate the integral of exp(-x) * x^order dx from interval_start to interval_end + """ + assert order in [0, 1, 2, 3], "order is only supported for 0, 1, 2 and 3" + + if order == 0: + return torch.exp(-interval_end) * (torch.exp(interval_end - interval_start) - 1) + elif order == 1: + return torch.exp(-interval_end) * ( + (interval_start + 1) * torch.exp(interval_end - interval_start) - (interval_end + 1) + ) + elif order == 2: + return torch.exp(-interval_end) * ( + (interval_start**2 + 2 * interval_start + 2) * torch.exp(interval_end - interval_start) + - (interval_end**2 + 2 * interval_end + 2) + ) + elif order == 3: + return torch.exp(-interval_end) * ( + (interval_start**3 + 3 * interval_start**2 + 6 * interval_start + 6) + * torch.exp(interval_end - interval_start) + - (interval_end**3 + 3 * interval_end**2 + 6 * interval_end + 6) + ) + + def get_coefficients_exponential_positive(self, order, interval_start, interval_end, tau): + """ + Calculate the integral of exp(x(1+tau^2)) * x^order dx from interval_start to interval_end + """ + assert order in [0, 1, 2, 3], "order is only supported for 0, 1, 2 and 3" + + # after change of variable(cov) + interval_end_cov = (1 + tau**2) * interval_end + interval_start_cov = (1 + tau**2) * interval_start + + if order == 0: + return ( + torch.exp(interval_end_cov) * (1 - torch.exp(-(interval_end_cov - interval_start_cov))) / (1 + tau**2) + ) + elif order == 1: + return ( + torch.exp(interval_end_cov) + * ( + (interval_end_cov - 1) + - (interval_start_cov - 1) * torch.exp(-(interval_end_cov - interval_start_cov)) + ) + / ((1 + tau**2) ** 2) + ) + elif order == 2: + return ( + torch.exp(interval_end_cov) + * ( + (interval_end_cov**2 - 2 * interval_end_cov + 2) + - (interval_start_cov**2 - 2 * interval_start_cov + 2) + * torch.exp(-(interval_end_cov - interval_start_cov)) + ) + / ((1 + tau**2) ** 3) + ) + elif order == 3: + return ( + torch.exp(interval_end_cov) + * ( + (interval_end_cov**3 - 3 * interval_end_cov**2 + 6 * interval_end_cov - 6) + - (interval_start_cov**3 - 3 * interval_start_cov**2 + 6 * interval_start_cov - 6) + * torch.exp(-(interval_end_cov - interval_start_cov)) + ) + / ((1 + tau**2) ** 4) + ) + + def lagrange_polynomial_coefficient(self, order, lambda_list): + """ + Calculate the coefficient of lagrange polynomial + """ + + assert order in [0, 1, 2, 3] + assert order == len(lambda_list) - 1 + if order == 0: + return [[1]] + elif order == 1: + return [ + [ + 1 / (lambda_list[0] - lambda_list[1]), + -lambda_list[1] / (lambda_list[0] - lambda_list[1]), + ], + [ + 1 / (lambda_list[1] - lambda_list[0]), + -lambda_list[0] / (lambda_list[1] - lambda_list[0]), + ], + ] + elif order == 2: + denominator1 = (lambda_list[0] - lambda_list[1]) * (lambda_list[0] - lambda_list[2]) + denominator2 = (lambda_list[1] - lambda_list[0]) * (lambda_list[1] - lambda_list[2]) + denominator3 = (lambda_list[2] - lambda_list[0]) * (lambda_list[2] - lambda_list[1]) + return [ + [ + 1 / denominator1, + (-lambda_list[1] - lambda_list[2]) / denominator1, + lambda_list[1] * lambda_list[2] / denominator1, + ], + [ + 1 / denominator2, + (-lambda_list[0] - lambda_list[2]) / denominator2, + lambda_list[0] * lambda_list[2] / denominator2, + ], + [ + 1 / denominator3, + (-lambda_list[0] - lambda_list[1]) / denominator3, + lambda_list[0] * lambda_list[1] / denominator3, + ], + ] + elif order == 3: + denominator1 = ( + (lambda_list[0] - lambda_list[1]) + * (lambda_list[0] - lambda_list[2]) + * (lambda_list[0] - lambda_list[3]) + ) + denominator2 = ( + (lambda_list[1] - lambda_list[0]) + * (lambda_list[1] - lambda_list[2]) + * (lambda_list[1] - lambda_list[3]) + ) + denominator3 = ( + (lambda_list[2] - lambda_list[0]) + * (lambda_list[2] - lambda_list[1]) + * (lambda_list[2] - lambda_list[3]) + ) + denominator4 = ( + (lambda_list[3] - lambda_list[0]) + * (lambda_list[3] - lambda_list[1]) + * (lambda_list[3] - lambda_list[2]) + ) + return [ + [ + 1 / denominator1, + (-lambda_list[1] - lambda_list[2] - lambda_list[3]) / denominator1, + ( + lambda_list[1] * lambda_list[2] + + lambda_list[1] * lambda_list[3] + + lambda_list[2] * lambda_list[3] + ) + / denominator1, + (-lambda_list[1] * lambda_list[2] * lambda_list[3]) / denominator1, + ], + [ + 1 / denominator2, + (-lambda_list[0] - lambda_list[2] - lambda_list[3]) / denominator2, + ( + lambda_list[0] * lambda_list[2] + + lambda_list[0] * lambda_list[3] + + lambda_list[2] * lambda_list[3] + ) + / denominator2, + (-lambda_list[0] * lambda_list[2] * lambda_list[3]) / denominator2, + ], + [ + 1 / denominator3, + (-lambda_list[0] - lambda_list[1] - lambda_list[3]) / denominator3, + ( + lambda_list[0] * lambda_list[1] + + lambda_list[0] * lambda_list[3] + + lambda_list[1] * lambda_list[3] + ) + / denominator3, + (-lambda_list[0] * lambda_list[1] * lambda_list[3]) / denominator3, + ], + [ + 1 / denominator4, + (-lambda_list[0] - lambda_list[1] - lambda_list[2]) / denominator4, + ( + lambda_list[0] * lambda_list[1] + + lambda_list[0] * lambda_list[2] + + lambda_list[1] * lambda_list[2] + ) + / denominator4, + (-lambda_list[0] * lambda_list[1] * lambda_list[2]) / denominator4, + ], + ] + + def get_coefficients_fn(self, order, interval_start, interval_end, lambda_list, tau): + assert order in [1, 2, 3, 4] + assert order == len(lambda_list), "the length of lambda list must be equal to the order" + coefficients = [] + lagrange_coefficient = self.lagrange_polynomial_coefficient(order - 1, lambda_list) + for i in range(order): + coefficient = 0 + for j in range(order): + if self.predict_x0: + coefficient += lagrange_coefficient[i][j] * self.get_coefficients_exponential_positive( + order - 1 - j, interval_start, interval_end, tau + ) + else: + coefficient += lagrange_coefficient[i][j] * self.get_coefficients_exponential_negative( + order - 1 - j, interval_start, interval_end + ) + coefficients.append(coefficient) + assert len(coefficients) == order, "the length of coefficients does not match the order" + return coefficients + + def stochastic_adams_bashforth_update( + self, + model_output: torch.Tensor, + *args, + sample: torch.Tensor, + noise: torch.Tensor, + order: int, + tau: torch.Tensor, + **kwargs, + ) -> torch.Tensor: + """ + One step for the SA-Predictor. + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model at the current timestep. + prev_timestep (`int`): + The previous discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + order (`int`): + The order of SA-Predictor at this timestep. + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + prev_timestep = args[0] if len(args) > 0 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 1: + sample = args[1] + else: + raise ValueError("missing `sample` as a required keyword argument") + if noise is None: + if len(args) > 2: + noise = args[2] + else: + raise ValueError("missing `noise` as a required keyword argument") + if order is None: + if len(args) > 3: + order = args[3] + else: + raise ValueError("missing `order` as a required keyword argument") + if tau is None: + if len(args) > 4: + tau = args[4] + else: + raise ValueError("missing `tau` as a required keyword argument") + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + model_output_list = self.model_outputs + sigma_t, sigma_s0 = ( + self.sigmas[self.step_index + 1], + self.sigmas[self.step_index], + ) + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s0 = torch.log(alpha_s0) - torch.log(sigma_s0) + + gradient_part = torch.zeros_like(sample) + h = lambda_t - lambda_s0 + lambda_list = [] + + for i in range(order): + si = self.step_index - i + alpha_si, sigma_si = self._sigma_to_alpha_sigma_t(self.sigmas[si]) + lambda_si = torch.log(alpha_si) - torch.log(sigma_si) + lambda_list.append(lambda_si) + + gradient_coefficients = self.get_coefficients_fn(order, lambda_s0, lambda_t, lambda_list, tau) + + x = sample + + if self.predict_x0: + if ( + order == 2 + ): ## if order = 2 we do a modification that does not influence the convergence order similar to unipc. Note: This is used only for few steps sampling. + # The added term is O(h^3). Empirically we find it will slightly improve the image quality. + # ODE case + # gradient_coefficients[0] += 1.0 * torch.exp(lambda_t) * (h ** 2 / 2 - (h - 1 + torch.exp(-h))) / (ns.marginal_lambda(t_prev_list[-1]) - ns.marginal_lambda(t_prev_list[-2])) + # gradient_coefficients[1] -= 1.0 * torch.exp(lambda_t) * (h ** 2 / 2 - (h - 1 + torch.exp(-h))) / (ns.marginal_lambda(t_prev_list[-1]) - ns.marginal_lambda(t_prev_list[-2])) + temp_sigma = self.sigmas[self.step_index - 1] + temp_alpha_s, temp_sigma_s = self._sigma_to_alpha_sigma_t(temp_sigma) + temp_lambda_s = torch.log(temp_alpha_s) - torch.log(temp_sigma_s) + gradient_coefficients[0] += ( + 1.0 + * torch.exp((1 + tau**2) * lambda_t) + * (h**2 / 2 - (h * (1 + tau**2) - 1 + torch.exp((1 + tau**2) * (-h))) / ((1 + tau**2) ** 2)) + / (lambda_s0 - temp_lambda_s) + ) + gradient_coefficients[1] -= ( + 1.0 + * torch.exp((1 + tau**2) * lambda_t) + * (h**2 / 2 - (h * (1 + tau**2) - 1 + torch.exp((1 + tau**2) * (-h))) / ((1 + tau**2) ** 2)) + / (lambda_s0 - temp_lambda_s) + ) + + for i in range(order): + if self.predict_x0: + gradient_part += ( + (1 + tau**2) + * sigma_t + * torch.exp(-(tau**2) * lambda_t) + * gradient_coefficients[i] + * model_output_list[-(i + 1)] + ) + else: + gradient_part += -(1 + tau**2) * alpha_t * gradient_coefficients[i] * model_output_list[-(i + 1)] + + if self.predict_x0: + noise_part = sigma_t * torch.sqrt(1 - torch.exp(-2 * tau**2 * h)) * noise + else: + noise_part = tau * sigma_t * torch.sqrt(torch.exp(2 * h) - 1) * noise + + if self.predict_x0: + x_t = torch.exp(-(tau**2) * h) * (sigma_t / sigma_s0) * x + gradient_part + noise_part + else: + x_t = (alpha_t / alpha_s0) * x + gradient_part + noise_part + + x_t = x_t.to(x.dtype) + return x_t + + def stochastic_adams_moulton_update( + self, + this_model_output: torch.Tensor, + *args, + last_sample: torch.Tensor, + last_noise: torch.Tensor, + this_sample: torch.Tensor, + order: int, + tau: torch.Tensor, + **kwargs, + ) -> torch.Tensor: + """ + One step for the SA-Corrector. + + Args: + this_model_output (`torch.Tensor`): + The model outputs at `x_t`. + this_timestep (`int`): + The current timestep `t`. + last_sample (`torch.Tensor`): + The generated sample before the last predictor `x_{t-1}`. + this_sample (`torch.Tensor`): + The generated sample after the last predictor `x_{t}`. + order (`int`): + The order of SA-Corrector at this step. + + Returns: + `torch.Tensor`: + The corrected sample tensor at the current timestep. + """ + + this_timestep = args[0] if len(args) > 0 else kwargs.pop("this_timestep", None) + if last_sample is None: + if len(args) > 1: + last_sample = args[1] + else: + raise ValueError("missing `last_sample` as a required keyword argument") + if last_noise is None: + if len(args) > 2: + last_noise = args[2] + else: + raise ValueError("missing `last_noise` as a required keyword argument") + if this_sample is None: + if len(args) > 3: + this_sample = args[3] + else: + raise ValueError("missing `this_sample` as a required keyword argument") + if order is None: + if len(args) > 4: + order = args[4] + else: + raise ValueError("missing `order` as a required keyword argument") + if tau is None: + if len(args) > 5: + tau = args[5] + else: + raise ValueError("missing `tau` as a required keyword argument") + if this_timestep is not None: + deprecate( + "this_timestep", + "1.0.0", + "Passing `this_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + model_output_list = self.model_outputs + sigma_t, sigma_s0 = ( + self.sigmas[self.step_index], + self.sigmas[self.step_index - 1], + ) + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s0 = torch.log(alpha_s0) - torch.log(sigma_s0) + gradient_part = torch.zeros_like(this_sample) + h = lambda_t - lambda_s0 + lambda_list = [] + for i in range(order): + si = self.step_index - i + alpha_si, sigma_si = self._sigma_to_alpha_sigma_t(self.sigmas[si]) + lambda_si = torch.log(alpha_si) - torch.log(sigma_si) + lambda_list.append(lambda_si) + + model_prev_list = model_output_list + [this_model_output] + + gradient_coefficients = self.get_coefficients_fn(order, lambda_s0, lambda_t, lambda_list, tau) + + x = last_sample + + if self.predict_x0: + if ( + order == 2 + ): ## if order = 2 we do a modification that does not influence the convergence order similar to UniPC. Note: This is used only for few steps sampling. + # The added term is O(h^3). Empirically we find it will slightly improve the image quality. + # ODE case + # gradient_coefficients[0] += 1.0 * torch.exp(lambda_t) * (h / 2 - (h - 1 + torch.exp(-h)) / h) + # gradient_coefficients[1] -= 1.0 * torch.exp(lambda_t) * (h / 2 - (h - 1 + torch.exp(-h)) / h) + gradient_coefficients[0] += ( + 1.0 + * torch.exp((1 + tau**2) * lambda_t) + * (h / 2 - (h * (1 + tau**2) - 1 + torch.exp((1 + tau**2) * (-h))) / ((1 + tau**2) ** 2 * h)) + ) + gradient_coefficients[1] -= ( + 1.0 + * torch.exp((1 + tau**2) * lambda_t) + * (h / 2 - (h * (1 + tau**2) - 1 + torch.exp((1 + tau**2) * (-h))) / ((1 + tau**2) ** 2 * h)) + ) + + for i in range(order): + if self.predict_x0: + gradient_part += ( + (1 + tau**2) + * sigma_t + * torch.exp(-(tau**2) * lambda_t) + * gradient_coefficients[i] + * model_prev_list[-(i + 1)] + ) + else: + gradient_part += -(1 + tau**2) * alpha_t * gradient_coefficients[i] * model_prev_list[-(i + 1)] + + if self.predict_x0: + noise_part = sigma_t * torch.sqrt(1 - torch.exp(-2 * tau**2 * h)) * last_noise + else: + noise_part = tau * sigma_t * torch.sqrt(torch.exp(2 * h) - 1) * last_noise + + if self.predict_x0: + x_t = torch.exp(-(tau**2) * h) * (sigma_t / sigma_s0) * x + gradient_part + noise_part + else: + x_t = (alpha_t / alpha_s0) * x + gradient_part + noise_part + + x_t = x_t.to(x.dtype) + return x_t + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + index_candidates = (schedule_timesteps == timestep).nonzero() + + if len(index_candidates) == 0: + step_index = len(self.timesteps) - 1 + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + elif len(index_candidates) > 1: + step_index = index_candidates[1].item() + else: + step_index = index_candidates[0].item() + + return step_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler._init_step_index + def _init_step_index(self, timestep): + """ + Initialize the step_index counter for the scheduler. + """ + + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + generator=None, + return_dict: bool = True, + ) -> Union[SchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the sample with + the SA-Solver. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_utils.SchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + if self.step_index is None: + self._init_step_index(timestep) + + use_corrector = self.step_index > 0 and self.last_sample is not None + + model_output_convert = self.convert_model_output(model_output, sample=sample) + + if use_corrector: + current_tau = self.tau_func(self.timestep_list[-1]) + sample = self.stochastic_adams_moulton_update( + this_model_output=model_output_convert, + last_sample=self.last_sample, + last_noise=self.last_noise, + this_sample=sample, + order=self.this_corrector_order, + tau=current_tau, + ) + + for i in range(max(self.config.predictor_order, self.config.corrector_order - 1) - 1): + self.model_outputs[i] = self.model_outputs[i + 1] + self.timestep_list[i] = self.timestep_list[i + 1] + + self.model_outputs[-1] = model_output_convert + self.timestep_list[-1] = timestep + + noise = randn_tensor( + model_output.shape, + generator=generator, + device=model_output.device, + dtype=model_output.dtype, + ) + + if self.config.lower_order_final: + this_predictor_order = min(self.config.predictor_order, len(self.timesteps) - self.step_index) + this_corrector_order = min(self.config.corrector_order, len(self.timesteps) - self.step_index + 1) + else: + this_predictor_order = self.config.predictor_order + this_corrector_order = self.config.corrector_order + + self.this_predictor_order = min(this_predictor_order, self.lower_order_nums + 1) # warmup for multistep + self.this_corrector_order = min(this_corrector_order, self.lower_order_nums + 2) # warmup for multistep + assert self.this_predictor_order > 0 + assert self.this_corrector_order > 0 + + self.last_sample = sample + self.last_noise = noise + + current_tau = self.tau_func(self.timestep_list[-1]) + prev_sample = self.stochastic_adams_bashforth_update( + model_output=model_output_convert, + sample=sample, + noise=noise, + order=self.this_predictor_order, + tau=current_tau, + ) + + if self.lower_order_nums < max(self.config.predictor_order, self.config.corrector_order - 1): + self.lower_order_nums += 1 + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return (prev_sample,) + + return SchedulerOutput(prev_sample=prev_sample) + + def scale_model_input(self, sample: torch.Tensor, *args, **kwargs) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as original_samples + # Move the self.alphas_cumprod to device to avoid redundant CPU to GPU data movement + # for the subsequent add_noise calls + self.alphas_cumprod = self.alphas_cumprod.to(device=original_samples.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=original_samples.dtype) + timesteps = timesteps.to(original_samples.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(original_samples.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(original_samples.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + noisy_samples = sqrt_alpha_prod * original_samples + sqrt_one_minus_alpha_prod * noise + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_scm.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_scm.py new file mode 100644 index 0000000000000000000000000000000000000000..23f47f42a30214e7cb4686e0969942f742e43f48 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_scm.py @@ -0,0 +1,265 @@ +# # Copyright 2024 Sana-Sprint Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This code is strongly influenced by https://github.com/pesser/pytorch_diffusion +# and https://github.com/hojonathanho/diffusion + +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..schedulers.scheduling_utils import SchedulerMixin +from ..utils import BaseOutput, logging +from ..utils.torch_utils import randn_tensor + + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->SCM +class SCMSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +class SCMScheduler(SchedulerMixin, ConfigMixin): + """ + `SCMScheduler` extends the denoising procedure introduced in denoising diffusion probabilistic models (DDPMs) with + non-Markovian guidance. This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass + documentation for the generic methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + prediction_type (`str`, defaults to `trigflow`): + Prediction type of the scheduler function. Currently only supports "trigflow". + sigma_data (`float`, defaults to 0.5): + The standard deviation of the noise added during multi-step inference. + """ + + # _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + prediction_type: str = "trigflow", + sigma_data: float = 0.5, + ): + """ + Initialize the SCM scheduler. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + prediction_type (`str`, defaults to `trigflow`): + Prediction type of the scheduler function. Currently only supports "trigflow". + sigma_data (`float`, defaults to 0.5): + The standard deviation of the noise added during multi-step inference. + """ + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # setable values + self.num_inference_steps = None + self.timesteps = torch.from_numpy(np.arange(0, num_train_timesteps)[::-1].copy().astype(np.int64)) + + self._step_index = None + self._begin_index = None + + @property + def step_index(self): + return self._step_index + + @property + def begin_index(self): + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def set_timesteps( + self, + num_inference_steps: int, + timesteps: torch.Tensor = None, + device: Union[str, torch.device] = None, + max_timesteps: float = 1.57080, + intermediate_timesteps: float = 1.3, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + timesteps (`torch.Tensor`, *optional*): + Custom timesteps to use for the denoising process. + max_timesteps (`float`, defaults to 1.57080): + The maximum timestep value used in the SCM scheduler. + intermediate_timesteps (`float`, *optional*, defaults to 1.3): + The intermediate timestep value used in SCM scheduler (only used when num_inference_steps=2). + """ + if num_inference_steps > self.config.num_train_timesteps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `self.config.train_timesteps`:" + f" {self.config.num_train_timesteps} as the unet model trained with this scheduler can only handle" + f" maximal {self.config.num_train_timesteps} timesteps." + ) + + if timesteps is not None and len(timesteps) != num_inference_steps + 1: + raise ValueError("If providing custom timesteps, `timesteps` must be of length `num_inference_steps + 1`.") + + if timesteps is not None and max_timesteps is not None: + raise ValueError("If providing custom timesteps, `max_timesteps` should not be provided.") + + if timesteps is None and max_timesteps is None: + raise ValueError("Should provide either `timesteps` or `max_timesteps`.") + + if intermediate_timesteps is not None and num_inference_steps != 2: + raise ValueError("Intermediate timesteps for SCM is not supported when num_inference_steps != 2.") + + self.num_inference_steps = num_inference_steps + + if timesteps is not None: + if isinstance(timesteps, list): + self.timesteps = torch.tensor(timesteps, device=device).float() + elif isinstance(timesteps, torch.Tensor): + self.timesteps = timesteps.to(device).float() + else: + raise ValueError(f"Unsupported timesteps type: {type(timesteps)}") + elif intermediate_timesteps is not None: + self.timesteps = torch.tensor([max_timesteps, intermediate_timesteps, 0], device=device).float() + else: + # max_timesteps=arctan(80/0.5)=1.56454 is the default from sCM paper, we choose a different value here + self.timesteps = torch.linspace(max_timesteps, 0, num_inference_steps + 1, device=device).float() + print(f"Set timesteps: {self.timesteps}") + + self._step_index = None + self._begin_index = None + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._init_step_index + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + def step( + self, + model_output: torch.FloatTensor, + timestep: float, + sample: torch.FloatTensor, + generator: torch.Generator = None, + return_dict: bool = True, + ) -> Union[SCMSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.FloatTensor`): + The direct output from learned diffusion model. + timestep (`float`): + The current discrete timestep in the diffusion chain. + sample (`torch.FloatTensor`): + A current instance of a sample created by the diffusion process. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_scm.SCMSchedulerOutput`] or `tuple`. + Returns: + [`~schedulers.scheduling_utils.SCMSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_scm.SCMSchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + if self.step_index is None: + self._init_step_index(timestep) + + # 2. compute alphas, betas + t = self.timesteps[self.step_index + 1] + s = self.timesteps[self.step_index] + + # 4. Different Parameterization: + parameterization = self.config.prediction_type + + if parameterization == "trigflow": + pred_x0 = torch.cos(s) * sample - torch.sin(s) * model_output + else: + raise ValueError(f"Unsupported parameterization: {parameterization}") + + # 5. Sample z ~ N(0, I), For MultiStep Inference + # Noise is not used for one-step sampling. + if len(self.timesteps) > 1: + noise = ( + randn_tensor(model_output.shape, device=model_output.device, generator=generator) + * self.config.sigma_data + ) + prev_sample = torch.cos(t) * pred_x0 + torch.sin(t) * noise + else: + prev_sample = pred_x0 + + self._step_index += 1 + + if not return_dict: + return (prev_sample, pred_x0) + + return SCMSchedulerOutput(prev_sample=prev_sample, pred_original_sample=pred_x0) + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_sde_ve.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_sde_ve.py new file mode 100644 index 0000000000000000000000000000000000000000..cedfbf7d6ad5c48075eeb18b67aa3ce36edc54eb --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_sde_ve.py @@ -0,0 +1,301 @@ +# Copyright 2024 Google Brain and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/yang-song/score_sde_pytorch + +import math +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import SchedulerMixin, SchedulerOutput + + +@dataclass +class SdeVeOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + prev_sample_mean (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Mean averaged `prev_sample` over previous timesteps. + """ + + prev_sample: torch.Tensor + prev_sample_mean: torch.Tensor + + +class ScoreSdeVeScheduler(SchedulerMixin, ConfigMixin): + """ + `ScoreSdeVeScheduler` is a variance exploding stochastic differential equation (SDE) scheduler. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + snr (`float`, defaults to 0.15): + A coefficient weighting the step from the `model_output` sample (from the network) to the random noise. + sigma_min (`float`, defaults to 0.01): + The initial noise scale for the sigma sequence in the sampling procedure. The minimum sigma should mirror + the distribution of the data. + sigma_max (`float`, defaults to 1348.0): + The maximum value used for the range of continuous timesteps passed into the model. + sampling_eps (`float`, defaults to 1e-5): + The end value of sampling where timesteps decrease progressively from 1 to epsilon. + correct_steps (`int`, defaults to 1): + The number of correction steps performed on a produced sample. + """ + + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 2000, + snr: float = 0.15, + sigma_min: float = 0.01, + sigma_max: float = 1348.0, + sampling_eps: float = 1e-5, + correct_steps: int = 1, + ): + # standard deviation of the initial noise distribution + self.init_noise_sigma = sigma_max + + # setable values + self.timesteps = None + + self.set_sigmas(num_train_timesteps, sigma_min, sigma_max, sampling_eps) + + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + def set_timesteps( + self, num_inference_steps: int, sampling_eps: float = None, device: Union[str, torch.device] = None + ): + """ + Sets the continuous timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + sampling_eps (`float`, *optional*): + The final timestep value (overrides value given during scheduler instantiation). + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + + """ + sampling_eps = sampling_eps if sampling_eps is not None else self.config.sampling_eps + + self.timesteps = torch.linspace(1, sampling_eps, num_inference_steps, device=device) + + def set_sigmas( + self, num_inference_steps: int, sigma_min: float = None, sigma_max: float = None, sampling_eps: float = None + ): + """ + Sets the noise scales used for the diffusion chain (to be run before inference). The sigmas control the weight + of the `drift` and `diffusion` components of the sample update. + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + sigma_min (`float`, optional): + The initial noise scale value (overrides value given during scheduler instantiation). + sigma_max (`float`, optional): + The final noise scale value (overrides value given during scheduler instantiation). + sampling_eps (`float`, optional): + The final timestep value (overrides value given during scheduler instantiation). + + """ + sigma_min = sigma_min if sigma_min is not None else self.config.sigma_min + sigma_max = sigma_max if sigma_max is not None else self.config.sigma_max + sampling_eps = sampling_eps if sampling_eps is not None else self.config.sampling_eps + if self.timesteps is None: + self.set_timesteps(num_inference_steps, sampling_eps) + + self.sigmas = sigma_min * (sigma_max / sigma_min) ** (self.timesteps / sampling_eps) + self.discrete_sigmas = torch.exp(torch.linspace(math.log(sigma_min), math.log(sigma_max), num_inference_steps)) + self.sigmas = torch.tensor([sigma_min * (sigma_max / sigma_min) ** t for t in self.timesteps]) + + def get_adjacent_sigma(self, timesteps, t): + return torch.where( + timesteps == 0, + torch.zeros_like(t.to(timesteps.device)), + self.discrete_sigmas[timesteps - 1].to(timesteps.device), + ) + + def step_pred( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[SdeVeOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_sde_ve.SdeVeOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_sde_ve.SdeVeOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_sde_ve.SdeVeOutput`] is returned, otherwise a tuple + is returned where the first element is the sample tensor. + + """ + if self.timesteps is None: + raise ValueError( + "`self.timesteps` is not set, you need to run 'set_timesteps' after creating the scheduler" + ) + + timestep = timestep * torch.ones( + sample.shape[0], device=sample.device + ) # torch.repeat_interleave(timestep, sample.shape[0]) + timesteps = (timestep * (len(self.timesteps) - 1)).long() + + # mps requires indices to be in the same device, so we use cpu as is the default with cuda + timesteps = timesteps.to(self.discrete_sigmas.device) + + sigma = self.discrete_sigmas[timesteps].to(sample.device) + adjacent_sigma = self.get_adjacent_sigma(timesteps, timestep).to(sample.device) + drift = torch.zeros_like(sample) + diffusion = (sigma**2 - adjacent_sigma**2) ** 0.5 + + # equation 6 in the paper: the model_output modeled by the network is grad_x log pt(x) + # also equation 47 shows the analog from SDE models to ancestral sampling methods + diffusion = diffusion.flatten() + while len(diffusion.shape) < len(sample.shape): + diffusion = diffusion.unsqueeze(-1) + drift = drift - diffusion**2 * model_output + + # equation 6: sample noise for the diffusion term of + noise = randn_tensor( + sample.shape, layout=sample.layout, generator=generator, device=sample.device, dtype=sample.dtype + ) + prev_sample_mean = sample - drift # subtract because `dt` is a small negative timestep + # TODO is the variable diffusion the correct scaling term for the noise? + prev_sample = prev_sample_mean + diffusion * noise # add impact of diffusion field g + + if not return_dict: + return (prev_sample, prev_sample_mean) + + return SdeVeOutput(prev_sample=prev_sample, prev_sample_mean=prev_sample_mean) + + def step_correct( + self, + model_output: torch.Tensor, + sample: torch.Tensor, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[SchedulerOutput, Tuple]: + """ + Correct the predicted sample based on the `model_output` of the network. This is often run repeatedly after + making the prediction for the previous timestep. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_sde_ve.SdeVeOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_sde_ve.SdeVeOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_sde_ve.SdeVeOutput`] is returned, otherwise a tuple + is returned where the first element is the sample tensor. + + """ + if self.timesteps is None: + raise ValueError( + "`self.timesteps` is not set, you need to run 'set_timesteps' after creating the scheduler" + ) + + # For small batch sizes, the paper "suggest replacing norm(z) with sqrt(d), where d is the dim. of z" + # sample noise for correction + noise = randn_tensor(sample.shape, layout=sample.layout, generator=generator).to(sample.device) + + # compute step size from the model_output, the noise, and the snr + grad_norm = torch.norm(model_output.reshape(model_output.shape[0], -1), dim=-1).mean() + noise_norm = torch.norm(noise.reshape(noise.shape[0], -1), dim=-1).mean() + step_size = (self.config.snr * noise_norm / grad_norm) ** 2 * 2 + step_size = step_size * torch.ones(sample.shape[0]).to(sample.device) + # self.repeat_scalar(step_size, sample.shape[0]) + + # compute corrected sample: model_output term and noise term + step_size = step_size.flatten() + while len(step_size.shape) < len(sample.shape): + step_size = step_size.unsqueeze(-1) + prev_sample_mean = sample + step_size * model_output + prev_sample = prev_sample_mean + ((step_size * 2) ** 0.5) * noise + + if not return_dict: + return (prev_sample,) + + return SchedulerOutput(prev_sample=prev_sample) + + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.Tensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + timesteps = timesteps.to(original_samples.device) + sigmas = self.discrete_sigmas.to(original_samples.device)[timesteps] + noise = ( + noise * sigmas[:, None, None, None] + if noise is not None + else torch.randn_like(original_samples) * sigmas[:, None, None, None] + ) + noisy_samples = noise + original_samples + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_sde_ve_flax.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_sde_ve_flax.py new file mode 100644 index 0000000000000000000000000000000000000000..db7f8beb4ce17475237bd1e8f2cdfea40a88b126 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_sde_ve_flax.py @@ -0,0 +1,280 @@ +# Copyright 2024 Google Brain and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This file is strongly influenced by https://github.com/yang-song/score_sde_pytorch + +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import flax +import jax +import jax.numpy as jnp +from jax import random + +from ..configuration_utils import ConfigMixin, register_to_config +from .scheduling_utils_flax import FlaxSchedulerMixin, FlaxSchedulerOutput, broadcast_to_shape_from_left + + +@flax.struct.dataclass +class ScoreSdeVeSchedulerState: + # setable values + timesteps: Optional[jnp.ndarray] = None + discrete_sigmas: Optional[jnp.ndarray] = None + sigmas: Optional[jnp.ndarray] = None + + @classmethod + def create(cls): + return cls() + + +@dataclass +class FlaxSdeVeOutput(FlaxSchedulerOutput): + """ + Output class for the ScoreSdeVeScheduler's step function output. + + Args: + state (`ScoreSdeVeSchedulerState`): + prev_sample (`jnp.ndarray` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample (x_{t-1}) of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + prev_sample_mean (`jnp.ndarray` of shape `(batch_size, num_channels, height, width)` for images): + Mean averaged `prev_sample`. Same as `prev_sample`, only mean-averaged over previous timesteps. + """ + + state: ScoreSdeVeSchedulerState + prev_sample: jnp.ndarray + prev_sample_mean: Optional[jnp.ndarray] = None + + +class FlaxScoreSdeVeScheduler(FlaxSchedulerMixin, ConfigMixin): + """ + The variance exploding stochastic differential equation (SDE) scheduler. + + For more information, see the original paper: https://huggingface.co/papers/2011.13456 + + [`~ConfigMixin`] takes care of storing all config attributes that are passed in the scheduler's `__init__` + function, such as `num_train_timesteps`. They can be accessed via `scheduler.config.num_train_timesteps`. + [`SchedulerMixin`] provides general loading and saving functionality via the [`SchedulerMixin.save_pretrained`] and + [`~SchedulerMixin.from_pretrained`] functions. + + Args: + num_train_timesteps (`int`): number of diffusion steps used to train the model. + snr (`float`): + coefficient weighting the step from the model_output sample (from the network) to the random noise. + sigma_min (`float`): + initial noise scale for sigma sequence in sampling procedure. The minimum sigma should mirror the + distribution of the data. + sigma_max (`float`): maximum value used for the range of continuous timesteps passed into the model. + sampling_eps (`float`): the end value of sampling, where timesteps decrease progressively from 1 to + epsilon. + correct_steps (`int`): number of correction steps performed on a produced sample. + """ + + @property + def has_state(self): + return True + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 2000, + snr: float = 0.15, + sigma_min: float = 0.01, + sigma_max: float = 1348.0, + sampling_eps: float = 1e-5, + correct_steps: int = 1, + ): + pass + + def create_state(self): + state = ScoreSdeVeSchedulerState.create() + return self.set_sigmas( + state, + self.config.num_train_timesteps, + self.config.sigma_min, + self.config.sigma_max, + self.config.sampling_eps, + ) + + def set_timesteps( + self, state: ScoreSdeVeSchedulerState, num_inference_steps: int, shape: Tuple = (), sampling_eps: float = None + ) -> ScoreSdeVeSchedulerState: + """ + Sets the continuous timesteps used for the diffusion chain. Supporting function to be run before inference. + + Args: + state (`ScoreSdeVeSchedulerState`): the `FlaxScoreSdeVeScheduler` state data class instance. + num_inference_steps (`int`): + the number of diffusion steps used when generating samples with a pre-trained model. + sampling_eps (`float`, optional): + final timestep value (overrides value given at Scheduler instantiation). + + """ + sampling_eps = sampling_eps if sampling_eps is not None else self.config.sampling_eps + + timesteps = jnp.linspace(1, sampling_eps, num_inference_steps) + return state.replace(timesteps=timesteps) + + def set_sigmas( + self, + state: ScoreSdeVeSchedulerState, + num_inference_steps: int, + sigma_min: float = None, + sigma_max: float = None, + sampling_eps: float = None, + ) -> ScoreSdeVeSchedulerState: + """ + Sets the noise scales used for the diffusion chain. Supporting function to be run before inference. + + The sigmas control the weight of the `drift` and `diffusion` components of sample update. + + Args: + state (`ScoreSdeVeSchedulerState`): the `FlaxScoreSdeVeScheduler` state data class instance. + num_inference_steps (`int`): + the number of diffusion steps used when generating samples with a pre-trained model. + sigma_min (`float`, optional): + initial noise scale value (overrides value given at Scheduler instantiation). + sigma_max (`float`, optional): + final noise scale value (overrides value given at Scheduler instantiation). + sampling_eps (`float`, optional): + final timestep value (overrides value given at Scheduler instantiation). + """ + sigma_min = sigma_min if sigma_min is not None else self.config.sigma_min + sigma_max = sigma_max if sigma_max is not None else self.config.sigma_max + sampling_eps = sampling_eps if sampling_eps is not None else self.config.sampling_eps + if state.timesteps is None: + state = self.set_timesteps(state, num_inference_steps, sampling_eps) + + discrete_sigmas = jnp.exp(jnp.linspace(jnp.log(sigma_min), jnp.log(sigma_max), num_inference_steps)) + sigmas = jnp.array([sigma_min * (sigma_max / sigma_min) ** t for t in state.timesteps]) + + return state.replace(discrete_sigmas=discrete_sigmas, sigmas=sigmas) + + def get_adjacent_sigma(self, state, timesteps, t): + return jnp.where(timesteps == 0, jnp.zeros_like(t), state.discrete_sigmas[timesteps - 1]) + + def step_pred( + self, + state: ScoreSdeVeSchedulerState, + model_output: jnp.ndarray, + timestep: int, + sample: jnp.ndarray, + key: jax.Array, + return_dict: bool = True, + ) -> Union[FlaxSdeVeOutput, Tuple]: + """ + Predict the sample at the previous timestep by reversing the SDE. Core function to propagate the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + state (`ScoreSdeVeSchedulerState`): the `FlaxScoreSdeVeScheduler` state data class instance. + model_output (`jnp.ndarray`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + generator: random number generator. + return_dict (`bool`): option for returning tuple rather than FlaxSdeVeOutput class + + Returns: + [`FlaxSdeVeOutput`] or `tuple`: [`FlaxSdeVeOutput`] if `return_dict` is True, otherwise a `tuple`. When + returning a tuple, the first element is the sample tensor. + + """ + if state.timesteps is None: + raise ValueError( + "`state.timesteps` is not set, you need to run 'set_timesteps' after creating the scheduler" + ) + + timestep = timestep * jnp.ones( + sample.shape[0], + ) + timesteps = (timestep * (len(state.timesteps) - 1)).long() + + sigma = state.discrete_sigmas[timesteps] + adjacent_sigma = self.get_adjacent_sigma(state, timesteps, timestep) + drift = jnp.zeros_like(sample) + diffusion = (sigma**2 - adjacent_sigma**2) ** 0.5 + + # equation 6 in the paper: the model_output modeled by the network is grad_x log pt(x) + # also equation 47 shows the analog from SDE models to ancestral sampling methods + diffusion = diffusion.flatten() + diffusion = broadcast_to_shape_from_left(diffusion, sample.shape) + drift = drift - diffusion**2 * model_output + + # equation 6: sample noise for the diffusion term of + key = random.split(key, num=1) + noise = random.normal(key=key, shape=sample.shape) + prev_sample_mean = sample - drift # subtract because `dt` is a small negative timestep + # TODO is the variable diffusion the correct scaling term for the noise? + prev_sample = prev_sample_mean + diffusion * noise # add impact of diffusion field g + + if not return_dict: + return (prev_sample, prev_sample_mean, state) + + return FlaxSdeVeOutput(prev_sample=prev_sample, prev_sample_mean=prev_sample_mean, state=state) + + def step_correct( + self, + state: ScoreSdeVeSchedulerState, + model_output: jnp.ndarray, + sample: jnp.ndarray, + key: jax.Array, + return_dict: bool = True, + ) -> Union[FlaxSdeVeOutput, Tuple]: + """ + Correct the predicted sample based on the output model_output of the network. This is often run repeatedly + after making the prediction for the previous timestep. + + Args: + state (`ScoreSdeVeSchedulerState`): the `FlaxScoreSdeVeScheduler` state data class instance. + model_output (`jnp.ndarray`): direct output from learned diffusion model. + sample (`jnp.ndarray`): + current instance of sample being created by diffusion process. + generator: random number generator. + return_dict (`bool`): option for returning tuple rather than FlaxSdeVeOutput class + + Returns: + [`FlaxSdeVeOutput`] or `tuple`: [`FlaxSdeVeOutput`] if `return_dict` is True, otherwise a `tuple`. When + returning a tuple, the first element is the sample tensor. + + """ + if state.timesteps is None: + raise ValueError( + "`state.timesteps` is not set, you need to run 'set_timesteps' after creating the scheduler" + ) + + # For small batch sizes, the paper "suggest replacing norm(z) with sqrt(d), where d is the dim. of z" + # sample noise for correction + key = random.split(key, num=1) + noise = random.normal(key=key, shape=sample.shape) + + # compute step size from the model_output, the noise, and the snr + grad_norm = jnp.linalg.norm(model_output) + noise_norm = jnp.linalg.norm(noise) + step_size = (self.config.snr * noise_norm / grad_norm) ** 2 * 2 + step_size = step_size * jnp.ones(sample.shape[0]) + + # compute corrected sample: model_output term and noise term + step_size = step_size.flatten() + step_size = broadcast_to_shape_from_left(step_size, sample.shape) + prev_sample_mean = sample + step_size * model_output + prev_sample = prev_sample_mean + ((step_size * 2) ** 0.5) * noise + + if not return_dict: + return (prev_sample, state) + + return FlaxSdeVeOutput(prev_sample=prev_sample, state=state) + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_tcd.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_tcd.py new file mode 100644 index 0000000000000000000000000000000000000000..6a27323aeba1b5676d022877140976a266866526 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_tcd.py @@ -0,0 +1,690 @@ +# Copyright 2024 Stanford University Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: This code is strongly influenced by https://github.com/pesser/pytorch_diffusion +# and https://github.com/hojonathanho/diffusion + +import math +from dataclasses import dataclass +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..schedulers.scheduling_utils import SchedulerMixin +from ..utils import BaseOutput, logging +from ..utils.torch_utils import randn_tensor + + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + + +@dataclass +class TCDSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_noised_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted noised sample `(x_{s})` based on the model output from the current timestep. + """ + + prev_sample: torch.Tensor + pred_noised_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +# Copied from diffusers.schedulers.scheduling_ddim.rescale_zero_terminal_snr +def rescale_zero_terminal_snr(betas: torch.Tensor) -> torch.Tensor: + """ + Rescales betas to have zero terminal SNR Based on https://huggingface.co/papers/2305.08891 (Algorithm 1) + + + Args: + betas (`torch.Tensor`): + the betas that the scheduler is being initialized with. + + Returns: + `torch.Tensor`: rescaled betas with zero terminal SNR + """ + # Convert betas to alphas_bar_sqrt + alphas = 1.0 - betas + alphas_cumprod = torch.cumprod(alphas, dim=0) + alphas_bar_sqrt = alphas_cumprod.sqrt() + + # Store old values. + alphas_bar_sqrt_0 = alphas_bar_sqrt[0].clone() + alphas_bar_sqrt_T = alphas_bar_sqrt[-1].clone() + + # Shift so the last timestep is zero. + alphas_bar_sqrt -= alphas_bar_sqrt_T + + # Scale so the first timestep is back to the old value. + alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T) + + # Convert alphas_bar_sqrt to betas + alphas_bar = alphas_bar_sqrt**2 # Revert sqrt + alphas = alphas_bar[1:] / alphas_bar[:-1] # Revert cumprod + alphas = torch.cat([alphas_bar[0:1], alphas]) + betas = 1 - alphas + + return betas + + +class TCDScheduler(SchedulerMixin, ConfigMixin): + """ + `TCDScheduler` incorporates the `Strategic Stochastic Sampling` introduced by the paper `Trajectory Consistency + Distillation`, extending the original Multistep Consistency Sampling to enable unrestricted trajectory traversal. + + This code is based on the official repo of TCD(https://github.com/jabir-zheng/TCD). + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. [`~ConfigMixin`] takes care of storing all config + attributes that are passed in the scheduler's `__init__` function, such as `num_train_timesteps`. They can be + accessed via `scheduler.config.num_train_timesteps`. [`SchedulerMixin`] provides general loading and saving + functionality via the [`SchedulerMixin.save_pretrained`] and [`~SchedulerMixin.from_pretrained`] functions. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + original_inference_steps (`int`, *optional*, defaults to 50): + The default number of inference steps used to generate a linearly-spaced timestep schedule, from which we + will ultimately take `num_inference_steps` evenly spaced timesteps to form the final timestep schedule. + clip_sample (`bool`, defaults to `True`): + Clip the predicted sample for numerical stability. + clip_sample_range (`float`, defaults to 1.0): + The maximum magnitude for sample clipping. Valid only when `clip_sample=True`. + set_alpha_to_one (`bool`, defaults to `True`): + Each diffusion step uses the alphas product value at that step and at the previous one. For the final step + there is no previous alpha. When this option is `True` the previous alpha product is fixed to `1`, + otherwise it uses the alpha value at step 0. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + thresholding (`bool`, defaults to `False`): + Whether to use the "dynamic thresholding" method. This is unsuitable for latent-space diffusion models such + as Stable Diffusion. + dynamic_thresholding_ratio (`float`, defaults to 0.995): + The ratio for the dynamic thresholding method. Valid only when `thresholding=True`. + sample_max_value (`float`, defaults to 1.0): + The threshold value for dynamic thresholding. Valid only when `thresholding=True`. + timestep_spacing (`str`, defaults to `"leading"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + timestep_scaling (`float`, defaults to 10.0): + The factor the timesteps will be multiplied by when calculating the consistency model boundary conditions + `c_skip` and `c_out`. Increasing this will decrease the approximation error (although the approximation + error at the default of `10.0` is already pretty small). + rescale_betas_zero_snr (`bool`, defaults to `False`): + Whether to rescale the betas to have zero terminal SNR. This enables the model to generate very bright and + dark samples instead of limiting it to samples with medium brightness. Loosely related to + [`--offset_noise`](https://github.com/huggingface/diffusers/blob/74fd735eb073eb1d774b1ab4154a0876eb82f055/examples/dreambooth/train_dreambooth.py#L506). + """ + + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.00085, + beta_end: float = 0.012, + beta_schedule: str = "scaled_linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + original_inference_steps: int = 50, + clip_sample: bool = False, + clip_sample_range: float = 1.0, + set_alpha_to_one: bool = True, + steps_offset: int = 0, + prediction_type: str = "epsilon", + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + sample_max_value: float = 1.0, + timestep_spacing: str = "leading", + timestep_scaling: float = 10.0, + rescale_betas_zero_snr: bool = False, + ): + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + # Rescale for zero SNR + if rescale_betas_zero_snr: + self.betas = rescale_zero_terminal_snr(self.betas) + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + # At every step in ddim, we are looking into the previous alphas_cumprod + # For the final step, there is no previous alphas_cumprod because we are already at 0 + # `set_alpha_to_one` decides whether we set this parameter simply to one or + # whether we use the final alpha of the "non-previous" one. + self.final_alpha_cumprod = torch.tensor(1.0) if set_alpha_to_one else self.alphas_cumprod[0] + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # setable values + self.num_inference_steps = None + self.timesteps = torch.from_numpy(np.arange(0, num_train_timesteps)[::-1].copy().astype(np.int64)) + self.custom_timesteps = False + + self._step_index = None + self._begin_index = None + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + indices = (schedule_timesteps == timestep).nonzero() + + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + pos = 1 if len(indices) > 1 else 0 + + return indices[pos].item() + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._init_step_index + def _init_step_index(self, timestep): + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + @property + def step_index(self): + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + timestep (`int`, *optional*): + The current timestep in the diffusion chain. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + # Copied from diffusers.schedulers.scheduling_ddim.DDIMScheduler._get_variance + def _get_variance(self, timestep, prev_timestep): + alpha_prod_t = self.alphas_cumprod[timestep] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + variance = (beta_prod_t_prev / beta_prod_t) * (1 - alpha_prod_t / alpha_prod_t_prev) + + return variance + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler._threshold_sample + def _threshold_sample(self, sample: torch.Tensor) -> torch.Tensor: + """ + "Dynamic thresholding: At each sampling step we set s to a certain percentile absolute pixel value in xt0 (the + prediction of x_0 at timestep t), and if s > 1, then we threshold xt0 to the range [-s, s] and then divide by + s. Dynamic thresholding pushes saturated pixels (those near -1 and 1) inwards, thereby actively preventing + pixels from saturation at each step. We find that dynamic thresholding results in significantly better + photorealism as well as better image-text alignment, especially when using very large guidance weights." + + https://huggingface.co/papers/2205.11487 + """ + dtype = sample.dtype + batch_size, channels, *remaining_dims = sample.shape + + if dtype not in (torch.float32, torch.float64): + sample = sample.float() # upcast for quantile calculation, and clamp not implemented for cpu half + + # Flatten sample for doing quantile calculation along each image + sample = sample.reshape(batch_size, channels * np.prod(remaining_dims)) + + abs_sample = sample.abs() # "a certain percentile absolute pixel value" + + s = torch.quantile(abs_sample, self.config.dynamic_thresholding_ratio, dim=1) + s = torch.clamp( + s, min=1, max=self.config.sample_max_value + ) # When clamped to min=1, equivalent to standard clipping to [-1, 1] + s = s.unsqueeze(1) # (batch_size, 1) because clamp will broadcast along dim=0 + sample = torch.clamp(sample, -s, s) / s # "we threshold xt0 to the range [-s, s] and then divide by s" + + sample = sample.reshape(batch_size, channels, *remaining_dims) + sample = sample.to(dtype) + + return sample + + def set_timesteps( + self, + num_inference_steps: Optional[int] = None, + device: Union[str, torch.device] = None, + original_inference_steps: Optional[int] = None, + timesteps: Optional[List[int]] = None, + strength: float = 1.0, + ): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`, *optional*): + The number of diffusion steps used when generating samples with a pre-trained model. If used, + `timesteps` must be `None`. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + original_inference_steps (`int`, *optional*): + The original number of inference steps, which will be used to generate a linearly-spaced timestep + schedule (which is different from the standard `diffusers` implementation). We will then take + `num_inference_steps` timesteps from this schedule, evenly spaced in terms of indices, and use that as + our final timestep schedule. If not set, this will default to the `original_inference_steps` attribute. + timesteps (`List[int]`, *optional*): + Custom timesteps used to support arbitrary spacing between timesteps. If `None`, then the default + timestep spacing strategy of equal spacing between timesteps on the training/distillation timestep + schedule is used. If `timesteps` is passed, `num_inference_steps` must be `None`. + strength (`float`, *optional*, defaults to 1.0): + Used to determine the number of timesteps used for inference when using img2img, inpaint, etc. + """ + # 0. Check inputs + if num_inference_steps is None and timesteps is None: + raise ValueError("Must pass exactly one of `num_inference_steps` or `custom_timesteps`.") + + if num_inference_steps is not None and timesteps is not None: + raise ValueError("Can only pass one of `num_inference_steps` or `custom_timesteps`.") + + # 1. Calculate the TCD original training/distillation timestep schedule. + original_steps = ( + original_inference_steps if original_inference_steps is not None else self.config.original_inference_steps + ) + + if original_inference_steps is None: + # default option, timesteps align with discrete inference steps + if original_steps > self.config.num_train_timesteps: + raise ValueError( + f"`original_steps`: {original_steps} cannot be larger than `self.config.train_timesteps`:" + f" {self.config.num_train_timesteps} as the unet model trained with this scheduler can only handle" + f" maximal {self.config.num_train_timesteps} timesteps." + ) + # TCD Timesteps Setting + # The skipping step parameter k from the paper. + k = self.config.num_train_timesteps // original_steps + # TCD Training/Distillation Steps Schedule + tcd_origin_timesteps = np.asarray(list(range(1, int(original_steps * strength) + 1))) * k - 1 + else: + # customised option, sampled timesteps can be any arbitrary value + tcd_origin_timesteps = np.asarray(list(range(0, int(self.config.num_train_timesteps * strength)))) + + # 2. Calculate the TCD inference timestep schedule. + if timesteps is not None: + # 2.1 Handle custom timestep schedules. + train_timesteps = set(tcd_origin_timesteps) + non_train_timesteps = [] + for i in range(1, len(timesteps)): + if timesteps[i] >= timesteps[i - 1]: + raise ValueError("`custom_timesteps` must be in descending order.") + + if timesteps[i] not in train_timesteps: + non_train_timesteps.append(timesteps[i]) + + if timesteps[0] >= self.config.num_train_timesteps: + raise ValueError( + f"`timesteps` must start before `self.config.train_timesteps`: {self.config.num_train_timesteps}." + ) + + # Raise warning if timestep schedule does not start with self.config.num_train_timesteps - 1 + if strength == 1.0 and timesteps[0] != self.config.num_train_timesteps - 1: + logger.warning( + f"The first timestep on the custom timestep schedule is {timesteps[0]}, not" + f" `self.config.num_train_timesteps - 1`: {self.config.num_train_timesteps - 1}. You may get" + f" unexpected results when using this timestep schedule." + ) + + # Raise warning if custom timestep schedule contains timesteps not on original timestep schedule + if non_train_timesteps: + logger.warning( + f"The custom timestep schedule contains the following timesteps which are not on the original" + f" training/distillation timestep schedule: {non_train_timesteps}. You may get unexpected results" + f" when using this timestep schedule." + ) + + # Raise warning if custom timestep schedule is longer than original_steps + if original_steps is not None: + if len(timesteps) > original_steps: + logger.warning( + f"The number of timesteps in the custom timestep schedule is {len(timesteps)}, which exceeds the" + f" the length of the timestep schedule used for training: {original_steps}. You may get some" + f" unexpected results when using this timestep schedule." + ) + else: + if len(timesteps) > self.config.num_train_timesteps: + logger.warning( + f"The number of timesteps in the custom timestep schedule is {len(timesteps)}, which exceeds the" + f" the length of the timestep schedule used for training: {self.config.num_train_timesteps}. You may get some" + f" unexpected results when using this timestep schedule." + ) + + timesteps = np.array(timesteps, dtype=np.int64) + self.num_inference_steps = len(timesteps) + self.custom_timesteps = True + + # Apply strength (e.g. for img2img pipelines) (see StableDiffusionImg2ImgPipeline.get_timesteps) + init_timestep = min(int(self.num_inference_steps * strength), self.num_inference_steps) + t_start = max(self.num_inference_steps - init_timestep, 0) + timesteps = timesteps[t_start * self.order :] + # TODO: also reset self.num_inference_steps? + else: + # 2.2 Create the "standard" TCD inference timestep schedule. + if num_inference_steps > self.config.num_train_timesteps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `self.config.train_timesteps`:" + f" {self.config.num_train_timesteps} as the unet model trained with this scheduler can only handle" + f" maximal {self.config.num_train_timesteps} timesteps." + ) + + if original_steps is not None: + skipping_step = len(tcd_origin_timesteps) // num_inference_steps + + if skipping_step < 1: + raise ValueError( + f"The combination of `original_steps x strength`: {original_steps} x {strength} is smaller than `num_inference_steps`: {num_inference_steps}. Make sure to either reduce `num_inference_steps` to a value smaller than {int(original_steps * strength)} or increase `strength` to a value higher than {float(num_inference_steps / original_steps)}." + ) + + self.num_inference_steps = num_inference_steps + + if original_steps is not None: + if num_inference_steps > original_steps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `original_inference_steps`:" + f" {original_steps} because the final timestep schedule will be a subset of the" + f" `original_inference_steps`-sized initial timestep schedule." + ) + else: + if num_inference_steps > self.config.num_train_timesteps: + raise ValueError( + f"`num_inference_steps`: {num_inference_steps} cannot be larger than `num_train_timesteps`:" + f" {self.config.num_train_timesteps} because the final timestep schedule will be a subset of the" + f" `num_train_timesteps`-sized initial timestep schedule." + ) + + # TCD Inference Steps Schedule + tcd_origin_timesteps = tcd_origin_timesteps[::-1].copy() + # Select (approximately) evenly spaced indices from tcd_origin_timesteps. + inference_indices = np.linspace(0, len(tcd_origin_timesteps), num=num_inference_steps, endpoint=False) + inference_indices = np.floor(inference_indices).astype(np.int64) + timesteps = tcd_origin_timesteps[inference_indices] + + self.timesteps = torch.from_numpy(timesteps).to(device=device, dtype=torch.long) + + self._step_index = None + self._begin_index = None + + def step( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + eta: float = 0.3, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[TCDSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + eta (`float`): + A stochastic parameter (referred to as `gamma` in the paper) used to control the stochasticity in every + step. When eta = 0, it represents deterministic sampling, whereas eta = 1 indicates full stochastic + sampling. + generator (`torch.Generator`, *optional*): + A random number generator. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_tcd.TCDSchedulerOutput`] or `tuple`. + Returns: + [`~schedulers.scheduling_utils.TCDSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_tcd.TCDSchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + if self.step_index is None: + self._init_step_index(timestep) + + assert 0 <= eta <= 1.0, "gamma must be less than or equal to 1.0" + + # 1. get previous step value + prev_step_index = self.step_index + 1 + if prev_step_index < len(self.timesteps): + prev_timestep = self.timesteps[prev_step_index] + else: + prev_timestep = torch.tensor(0) + + timestep_s = torch.floor((1 - eta) * prev_timestep).to(dtype=torch.long) + + # 2. compute alphas, betas + alpha_prod_t = self.alphas_cumprod[timestep] + beta_prod_t = 1 - alpha_prod_t + + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.final_alpha_cumprod + + alpha_prod_s = self.alphas_cumprod[timestep_s] + beta_prod_s = 1 - alpha_prod_s + + # 3. Compute the predicted noised sample x_s based on the model parameterization + if self.config.prediction_type == "epsilon": # noise-prediction + pred_original_sample = (sample - beta_prod_t.sqrt() * model_output) / alpha_prod_t.sqrt() + pred_epsilon = model_output + pred_noised_sample = alpha_prod_s.sqrt() * pred_original_sample + beta_prod_s.sqrt() * pred_epsilon + elif self.config.prediction_type == "sample": # x-prediction + pred_original_sample = model_output + pred_epsilon = (sample - alpha_prod_t ** (0.5) * pred_original_sample) / beta_prod_t ** (0.5) + pred_noised_sample = alpha_prod_s.sqrt() * pred_original_sample + beta_prod_s.sqrt() * pred_epsilon + elif self.config.prediction_type == "v_prediction": # v-prediction + pred_original_sample = (alpha_prod_t**0.5) * sample - (beta_prod_t**0.5) * model_output + pred_epsilon = (alpha_prod_t**0.5) * model_output + (beta_prod_t**0.5) * sample + pred_noised_sample = alpha_prod_s.sqrt() * pred_original_sample + beta_prod_s.sqrt() * pred_epsilon + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample` or" + " `v_prediction` for `TCDScheduler`." + ) + + # 4. Sample and inject noise z ~ N(0, I) for MultiStep Inference + # Noise is not used on the final timestep of the timestep schedule. + # This also means that noise is not used for one-step sampling. + # Eta (referred to as "gamma" in the paper) was introduced to control the stochasticity in every step. + # When eta = 0, it represents deterministic sampling, whereas eta = 1 indicates full stochastic sampling. + if eta > 0: + if self.step_index != self.num_inference_steps - 1: + noise = randn_tensor( + model_output.shape, generator=generator, device=model_output.device, dtype=pred_noised_sample.dtype + ) + prev_sample = (alpha_prod_t_prev / alpha_prod_s).sqrt() * pred_noised_sample + ( + 1 - alpha_prod_t_prev / alpha_prod_s + ).sqrt() * noise + else: + prev_sample = pred_noised_sample + else: + prev_sample = pred_noised_sample + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return (prev_sample, pred_noised_sample) + + return TCDSchedulerOutput(prev_sample=prev_sample, pred_noised_sample=pred_noised_sample) + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as original_samples + # Move the self.alphas_cumprod to device to avoid redundant CPU to GPU data movement + # for the subsequent add_noise calls + self.alphas_cumprod = self.alphas_cumprod.to(device=original_samples.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=original_samples.dtype) + timesteps = timesteps.to(original_samples.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(original_samples.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(original_samples.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + noisy_samples = sqrt_alpha_prod * original_samples + sqrt_one_minus_alpha_prod * noise + return noisy_samples + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.get_velocity + def get_velocity(self, sample: torch.Tensor, noise: torch.Tensor, timesteps: torch.IntTensor) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as sample + self.alphas_cumprod = self.alphas_cumprod.to(device=sample.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=sample.dtype) + timesteps = timesteps.to(sample.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(sample.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(sample.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + velocity = sqrt_alpha_prod * noise - sqrt_one_minus_alpha_prod * sample + return velocity + + def __len__(self): + return self.config.num_train_timesteps + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.previous_timestep + def previous_timestep(self, timestep): + if self.custom_timesteps or self.num_inference_steps: + index = (self.timesteps == timestep).nonzero(as_tuple=True)[0][0] + if index == self.timesteps.shape[0] - 1: + prev_t = torch.tensor(-1) + else: + prev_t = self.timesteps[index + 1] + else: + prev_t = timestep - 1 + return prev_t diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_unclip.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_unclip.py new file mode 100644 index 0000000000000000000000000000000000000000..46c855c9c1de358a345e790512541f50e5e6b58b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_unclip.py @@ -0,0 +1,355 @@ +# Copyright 2024 Kakao Brain and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import math +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from ..utils.torch_utils import randn_tensor +from .scheduling_utils import SchedulerMixin + + +@dataclass +# Copied from diffusers.schedulers.scheduling_ddpm.DDPMSchedulerOutput with DDPM->UnCLIP +class UnCLIPSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's `step` function output. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + pred_original_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + The predicted denoised sample `(x_{0})` based on the model output from the current timestep. + `pred_original_sample` can be used to preview progress or for guidance. + """ + + prev_sample: torch.Tensor + pred_original_sample: Optional[torch.Tensor] = None + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +class UnCLIPScheduler(SchedulerMixin, ConfigMixin): + """ + NOTE: do not use this scheduler. The DDPM scheduler has been updated to support the changes made here. This + scheduler will be removed and replaced with DDPM. + + This is a modified DDPM Scheduler specifically for the karlo unCLIP model. + + This scheduler has some minor variations in how it calculates the learned range variance and dynamically + re-calculates betas based off the timesteps it is skipping. + + The scheduler also uses a slightly different step ratio when computing timesteps to use for inference. + + See [`~DDPMScheduler`] for more information on DDPM scheduling + + Args: + num_train_timesteps (`int`): number of diffusion steps used to train the model. + variance_type (`str`): + options to clip the variance used when adding noise to the denoised sample. Choose from `fixed_small_log` + or `learned_range`. + clip_sample (`bool`, default `True`): + option to clip predicted sample between `-clip_sample_range` and `clip_sample_range` for numerical + stability. + clip_sample_range (`float`, default `1.0`): + The range to clip the sample between. See `clip_sample`. + prediction_type (`str`, default `epsilon`, optional): + prediction type of the scheduler function, one of `epsilon` (predicting the noise of the diffusion process) + or `sample` (directly predicting the noisy sample`) + """ + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + variance_type: str = "fixed_small_log", + clip_sample: bool = True, + clip_sample_range: Optional[float] = 1.0, + prediction_type: str = "epsilon", + beta_schedule: str = "squaredcos_cap_v2", + ): + if beta_schedule != "squaredcos_cap_v2": + raise ValueError("UnCLIPScheduler only supports `beta_schedule`: 'squaredcos_cap_v2'") + + self.betas = betas_for_alpha_bar(num_train_timesteps) + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + self.one = torch.tensor(1.0) + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + # setable values + self.num_inference_steps = None + self.timesteps = torch.from_numpy(np.arange(0, num_train_timesteps)[::-1].copy()) + + self.variance_type = variance_type + + def scale_model_input(self, sample: torch.Tensor, timestep: Optional[int] = None) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): input sample + timestep (`int`, optional): current timestep + + Returns: + `torch.Tensor`: scaled input sample + """ + return sample + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain. Supporting function to be run before inference. + + Note that this scheduler uses a slightly different step ratio than the other diffusers schedulers. The + different step ratio is to mimic the original karlo implementation and does not affect the quality or accuracy + of the results. + + Args: + num_inference_steps (`int`): + the number of diffusion steps used when generating samples with a pre-trained model. + """ + self.num_inference_steps = num_inference_steps + step_ratio = (self.config.num_train_timesteps - 1) / (self.num_inference_steps - 1) + timesteps = (np.arange(0, num_inference_steps) * step_ratio).round()[::-1].copy().astype(np.int64) + self.timesteps = torch.from_numpy(timesteps).to(device) + + def _get_variance(self, t, prev_timestep=None, predicted_variance=None, variance_type=None): + if prev_timestep is None: + prev_timestep = t - 1 + + alpha_prod_t = self.alphas_cumprod[t] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.one + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + if prev_timestep == t - 1: + beta = self.betas[t] + else: + beta = 1 - alpha_prod_t / alpha_prod_t_prev + + # For t > 0, compute predicted variance βt (see formula (6) and (7) from https://huggingface.co/papers/2006.11239) + # and sample from it to get previous sample + # x_{t-1} ~ N(pred_prev_sample, variance) == add variance to pred_sample + variance = beta_prod_t_prev / beta_prod_t * beta + + if variance_type is None: + variance_type = self.config.variance_type + + # hacks - were probably added for training stability + if variance_type == "fixed_small_log": + variance = torch.log(torch.clamp(variance, min=1e-20)) + variance = torch.exp(0.5 * variance) + elif variance_type == "learned_range": + # NOTE difference with DDPM scheduler + min_log = variance.log() + max_log = beta.log() + + frac = (predicted_variance + 1) / 2 + variance = frac * max_log + (1 - frac) * min_log + + return variance + + def step( + self, + model_output: torch.Tensor, + timestep: int, + sample: torch.Tensor, + prev_timestep: Optional[int] = None, + generator=None, + return_dict: bool = True, + ) -> Union[UnCLIPSchedulerOutput, Tuple]: + """ + Predict the sample at the previous timestep by reversing the SDE. Core function to propagate the diffusion + process from the learned model outputs (most often the predicted noise). + + Args: + model_output (`torch.Tensor`): direct output from learned diffusion model. + timestep (`int`): current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + current instance of sample being created by diffusion process. + prev_timestep (`int`, *optional*): The previous timestep to predict the previous sample at. + Used to dynamically compute beta. If not given, `t-1` is used and the pre-computed beta is used. + generator: random number generator. + return_dict (`bool`): option for returning tuple rather than UnCLIPSchedulerOutput class + + Returns: + [`~schedulers.scheduling_utils.UnCLIPSchedulerOutput`] or `tuple`: + [`~schedulers.scheduling_utils.UnCLIPSchedulerOutput`] if `return_dict` is True, otherwise a `tuple`. When + returning a tuple, the first element is the sample tensor. + + """ + t = timestep + + if model_output.shape[1] == sample.shape[1] * 2 and self.variance_type == "learned_range": + model_output, predicted_variance = torch.split(model_output, sample.shape[1], dim=1) + else: + predicted_variance = None + + # 1. compute alphas, betas + if prev_timestep is None: + prev_timestep = t - 1 + + alpha_prod_t = self.alphas_cumprod[t] + alpha_prod_t_prev = self.alphas_cumprod[prev_timestep] if prev_timestep >= 0 else self.one + beta_prod_t = 1 - alpha_prod_t + beta_prod_t_prev = 1 - alpha_prod_t_prev + + if prev_timestep == t - 1: + beta = self.betas[t] + alpha = self.alphas[t] + else: + beta = 1 - alpha_prod_t / alpha_prod_t_prev + alpha = 1 - beta + + # 2. compute predicted original sample from predicted noise also called + # "predicted x_0" of formula (15) from https://huggingface.co/papers/2006.11239 + if self.config.prediction_type == "epsilon": + pred_original_sample = (sample - beta_prod_t ** (0.5) * model_output) / alpha_prod_t ** (0.5) + elif self.config.prediction_type == "sample": + pred_original_sample = model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon` or `sample`" + " for the UnCLIPScheduler." + ) + + # 3. Clip "predicted x_0" + if self.config.clip_sample: + pred_original_sample = torch.clamp( + pred_original_sample, -self.config.clip_sample_range, self.config.clip_sample_range + ) + + # 4. Compute coefficients for pred_original_sample x_0 and current sample x_t + # See formula (7) from https://huggingface.co/papers/2006.11239 + pred_original_sample_coeff = (alpha_prod_t_prev ** (0.5) * beta) / beta_prod_t + current_sample_coeff = alpha ** (0.5) * beta_prod_t_prev / beta_prod_t + + # 5. Compute predicted previous sample µ_t + # See formula (7) from https://huggingface.co/papers/2006.11239 + pred_prev_sample = pred_original_sample_coeff * pred_original_sample + current_sample_coeff * sample + + # 6. Add noise + variance = 0 + if t > 0: + variance_noise = randn_tensor( + model_output.shape, dtype=model_output.dtype, generator=generator, device=model_output.device + ) + + variance = self._get_variance( + t, + predicted_variance=predicted_variance, + prev_timestep=prev_timestep, + ) + + if self.variance_type == "fixed_small_log": + variance = variance + elif self.variance_type == "learned_range": + variance = (0.5 * variance).exp() + else: + raise ValueError( + f"variance_type given as {self.variance_type} must be one of `fixed_small_log` or `learned_range`" + " for the UnCLIPScheduler." + ) + + variance = variance * variance_noise + + pred_prev_sample = pred_prev_sample + variance + + if not return_dict: + return ( + pred_prev_sample, + pred_original_sample, + ) + + return UnCLIPSchedulerOutput(prev_sample=pred_prev_sample, pred_original_sample=pred_original_sample) + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure alphas_cumprod and timestep have same device and dtype as original_samples + # Move the self.alphas_cumprod to device to avoid redundant CPU to GPU data movement + # for the subsequent add_noise calls + self.alphas_cumprod = self.alphas_cumprod.to(device=original_samples.device) + alphas_cumprod = self.alphas_cumprod.to(dtype=original_samples.dtype) + timesteps = timesteps.to(original_samples.device) + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + while len(sqrt_alpha_prod.shape) < len(original_samples.shape): + sqrt_alpha_prod = sqrt_alpha_prod.unsqueeze(-1) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + while len(sqrt_one_minus_alpha_prod.shape) < len(original_samples.shape): + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.unsqueeze(-1) + + noisy_samples = sqrt_alpha_prod * original_samples + sqrt_one_minus_alpha_prod * noise + return noisy_samples diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_unipc_multistep.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_unipc_multistep.py new file mode 100644 index 0000000000000000000000000000000000000000..b4566674923480769d12f879bc40154004ea92e1 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_unipc_multistep.py @@ -0,0 +1,1076 @@ +# Copyright 2024 TSAIL Team and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# DISCLAIMER: check https://huggingface.co/papers/2302.04867 and https://github.com/wl-zhao/UniPC for more info +# The codebase is modified based on https://github.com/huggingface/diffusers/blob/main/src/diffusers/schedulers/scheduling_dpmsolver_multistep.py + +import math +from typing import List, Optional, Tuple, Union + +import numpy as np +import torch + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import deprecate, is_scipy_available +from .scheduling_utils import KarrasDiffusionSchedulers, SchedulerMixin, SchedulerOutput + + +if is_scipy_available(): + import scipy.stats + + +# Copied from diffusers.schedulers.scheduling_ddpm.betas_for_alpha_bar +def betas_for_alpha_bar( + num_diffusion_timesteps, + max_beta=0.999, + alpha_transform_type="cosine", +): + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + alpha_transform_type (`str`, *optional*, default to `cosine`): the type of noise schedule for alpha_bar. + Choose from `cosine` or `exp` + + Returns: + betas (`np.ndarray`): the betas used by the scheduler to step the model outputs + """ + if alpha_transform_type == "cosine": + + def alpha_bar_fn(t): + return math.cos((t + 0.008) / 1.008 * math.pi / 2) ** 2 + + elif alpha_transform_type == "exp": + + def alpha_bar_fn(t): + return math.exp(t * -12.0) + + else: + raise ValueError(f"Unsupported alpha_transform_type: {alpha_transform_type}") + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar_fn(t2) / alpha_bar_fn(t1), max_beta)) + return torch.tensor(betas, dtype=torch.float32) + + +# Copied from diffusers.schedulers.scheduling_ddim.rescale_zero_terminal_snr +def rescale_zero_terminal_snr(betas): + """ + Rescales betas to have zero terminal SNR Based on https://huggingface.co/papers/2305.08891 (Algorithm 1) + + + Args: + betas (`torch.Tensor`): + the betas that the scheduler is being initialized with. + + Returns: + `torch.Tensor`: rescaled betas with zero terminal SNR + """ + # Convert betas to alphas_bar_sqrt + alphas = 1.0 - betas + alphas_cumprod = torch.cumprod(alphas, dim=0) + alphas_bar_sqrt = alphas_cumprod.sqrt() + + # Store old values. + alphas_bar_sqrt_0 = alphas_bar_sqrt[0].clone() + alphas_bar_sqrt_T = alphas_bar_sqrt[-1].clone() + + # Shift so the last timestep is zero. + alphas_bar_sqrt -= alphas_bar_sqrt_T + + # Scale so the first timestep is back to the old value. + alphas_bar_sqrt *= alphas_bar_sqrt_0 / (alphas_bar_sqrt_0 - alphas_bar_sqrt_T) + + # Convert alphas_bar_sqrt to betas + alphas_bar = alphas_bar_sqrt**2 # Revert sqrt + alphas = alphas_bar[1:] / alphas_bar[:-1] # Revert cumprod + alphas = torch.cat([alphas_bar[0:1], alphas]) + betas = 1 - alphas + + return betas + + +class UniPCMultistepScheduler(SchedulerMixin, ConfigMixin): + """ + `UniPCMultistepScheduler` is a training-free framework designed for the fast sampling of diffusion models. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_train_timesteps (`int`, defaults to 1000): + The number of diffusion steps to train the model. + beta_start (`float`, defaults to 0.0001): + The starting `beta` value of inference. + beta_end (`float`, defaults to 0.02): + The final `beta` value. + beta_schedule (`str`, defaults to `"linear"`): + The beta schedule, a mapping from a beta range to a sequence of betas for stepping the model. Choose from + `linear`, `scaled_linear`, or `squaredcos_cap_v2`. + trained_betas (`np.ndarray`, *optional*): + Pass an array of betas directly to the constructor to bypass `beta_start` and `beta_end`. + solver_order (`int`, default `2`): + The UniPC order which can be any positive integer. The effective order of accuracy is `solver_order + 1` + due to the UniC. It is recommended to use `solver_order=2` for guided sampling, and `solver_order=3` for + unconditional sampling. + prediction_type (`str`, defaults to `epsilon`, *optional*): + Prediction type of the scheduler function; can be `epsilon` (predicts the noise of the diffusion process), + `sample` (directly predicts the noisy sample`) or `v_prediction` (see section 2.4 of [Imagen + Video](https://imagen.research.google/video/paper.pdf) paper). + thresholding (`bool`, defaults to `False`): + Whether to use the "dynamic thresholding" method. This is unsuitable for latent-space diffusion models such + as Stable Diffusion. + dynamic_thresholding_ratio (`float`, defaults to 0.995): + The ratio for the dynamic thresholding method. Valid only when `thresholding=True`. + sample_max_value (`float`, defaults to 1.0): + The threshold value for dynamic thresholding. Valid only when `thresholding=True` and `predict_x0=True`. + predict_x0 (`bool`, defaults to `True`): + Whether to use the updating algorithm on the predicted x0. + solver_type (`str`, default `bh2`): + Solver type for UniPC. It is recommended to use `bh1` for unconditional sampling when steps < 10, and `bh2` + otherwise. + lower_order_final (`bool`, default `True`): + Whether to use lower-order solvers in the final steps. Only valid for < 15 inference steps. This can + stabilize the sampling of DPMSolver for steps < 15, especially for steps <= 10. + disable_corrector (`list`, default `[]`): + Decides which step to disable the corrector to mitigate the misalignment between `epsilon_theta(x_t, c)` + and `epsilon_theta(x_t^c, c)` which can influence convergence for a large guidance scale. Corrector is + usually disabled during the first few steps. + solver_p (`SchedulerMixin`, default `None`): + Any other scheduler that if specified, the algorithm becomes `solver_p + UniC`. + use_karras_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use Karras sigmas for step sizes in the noise schedule during the sampling process. If `True`, + the sigmas are determined according to a sequence of noise levels {σi}. + use_exponential_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use exponential sigmas for step sizes in the noise schedule during the sampling process. + use_beta_sigmas (`bool`, *optional*, defaults to `False`): + Whether to use beta sigmas for step sizes in the noise schedule during the sampling process. Refer to [Beta + Sampling is All You Need](https://huggingface.co/papers/2407.12173) for more information. + timestep_spacing (`str`, defaults to `"linspace"`): + The way the timesteps should be scaled. Refer to Table 2 of the [Common Diffusion Noise Schedules and + Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) for more information. + steps_offset (`int`, defaults to 0): + An offset added to the inference steps, as required by some model families. + final_sigmas_type (`str`, defaults to `"zero"`): + The final `sigma` value for the noise schedule during the sampling process. If `"sigma_min"`, the final + sigma is the same as the last sigma in the training schedule. If `zero`, the final sigma is set to 0. + rescale_betas_zero_snr (`bool`, defaults to `False`): + Whether to rescale the betas to have zero terminal SNR. This enables the model to generate very bright and + dark samples instead of limiting it to samples with medium brightness. Loosely related to + [`--offset_noise`](https://github.com/huggingface/diffusers/blob/74fd735eb073eb1d774b1ab4154a0876eb82f055/examples/dreambooth/train_dreambooth.py#L506). + """ + + _compatibles = [e.name for e in KarrasDiffusionSchedulers] + order = 1 + + @register_to_config + def __init__( + self, + num_train_timesteps: int = 1000, + beta_start: float = 0.0001, + beta_end: float = 0.02, + beta_schedule: str = "linear", + trained_betas: Optional[Union[np.ndarray, List[float]]] = None, + solver_order: int = 2, + prediction_type: str = "epsilon", + thresholding: bool = False, + dynamic_thresholding_ratio: float = 0.995, + sample_max_value: float = 1.0, + predict_x0: bool = True, + solver_type: str = "bh2", + lower_order_final: bool = True, + disable_corrector: List[int] = [], + solver_p: SchedulerMixin = None, + use_karras_sigmas: Optional[bool] = False, + use_exponential_sigmas: Optional[bool] = False, + use_beta_sigmas: Optional[bool] = False, + use_flow_sigmas: Optional[bool] = False, + flow_shift: Optional[float] = 1.0, + timestep_spacing: str = "linspace", + steps_offset: int = 0, + final_sigmas_type: Optional[str] = "zero", # "zero", "sigma_min" + rescale_betas_zero_snr: bool = False, + ): + if self.config.use_beta_sigmas and not is_scipy_available(): + raise ImportError("Make sure to install scipy if you want to use beta sigmas.") + if sum([self.config.use_beta_sigmas, self.config.use_exponential_sigmas, self.config.use_karras_sigmas]) > 1: + raise ValueError( + "Only one of `config.use_beta_sigmas`, `config.use_exponential_sigmas`, `config.use_karras_sigmas` can be used." + ) + if trained_betas is not None: + self.betas = torch.tensor(trained_betas, dtype=torch.float32) + elif beta_schedule == "linear": + self.betas = torch.linspace(beta_start, beta_end, num_train_timesteps, dtype=torch.float32) + elif beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + self.betas = torch.linspace(beta_start**0.5, beta_end**0.5, num_train_timesteps, dtype=torch.float32) ** 2 + elif beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + self.betas = betas_for_alpha_bar(num_train_timesteps) + else: + raise NotImplementedError(f"{beta_schedule} is not implemented for {self.__class__}") + + if rescale_betas_zero_snr: + self.betas = rescale_zero_terminal_snr(self.betas) + + self.alphas = 1.0 - self.betas + self.alphas_cumprod = torch.cumprod(self.alphas, dim=0) + + if rescale_betas_zero_snr: + # Close to 0 without being 0 so first sigma is not inf + # FP16 smallest positive subnormal works well here + self.alphas_cumprod[-1] = 2**-24 + + # Currently we only support VP-type noise schedule + self.alpha_t = torch.sqrt(self.alphas_cumprod) + self.sigma_t = torch.sqrt(1 - self.alphas_cumprod) + self.lambda_t = torch.log(self.alpha_t) - torch.log(self.sigma_t) + self.sigmas = ((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5 + + # standard deviation of the initial noise distribution + self.init_noise_sigma = 1.0 + + if solver_type not in ["bh1", "bh2"]: + if solver_type in ["midpoint", "heun", "logrho"]: + self.register_to_config(solver_type="bh2") + else: + raise NotImplementedError(f"{solver_type} is not implemented for {self.__class__}") + + self.predict_x0 = predict_x0 + # setable values + self.num_inference_steps = None + timesteps = np.linspace(0, num_train_timesteps - 1, num_train_timesteps, dtype=np.float32)[::-1].copy() + self.timesteps = torch.from_numpy(timesteps) + self.model_outputs = [None] * solver_order + self.timestep_list = [None] * solver_order + self.lower_order_nums = 0 + self.disable_corrector = disable_corrector + self.solver_p = solver_p + self.last_sample = None + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + @property + def step_index(self): + """ + The index counter for current timestep. It will increase 1 after each scheduler step. + """ + return self._step_index + + @property + def begin_index(self): + """ + The index for the first timestep. It should be set from pipeline with `set_begin_index` method. + """ + return self._begin_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.set_begin_index + def set_begin_index(self, begin_index: int = 0): + """ + Sets the begin index for the scheduler. This function should be run from pipeline before the inference. + + Args: + begin_index (`int`): + The begin index for the scheduler. + """ + self._begin_index = begin_index + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + """ + # "linspace", "leading", "trailing" corresponds to annotation of Table 2. of https://huggingface.co/papers/2305.08891 + if self.config.timestep_spacing == "linspace": + timesteps = ( + np.linspace(0, self.config.num_train_timesteps - 1, num_inference_steps + 1) + .round()[::-1][:-1] + .copy() + .astype(np.int64) + ) + elif self.config.timestep_spacing == "leading": + step_ratio = self.config.num_train_timesteps // (num_inference_steps + 1) + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = (np.arange(0, num_inference_steps + 1) * step_ratio).round()[::-1][:-1].copy().astype(np.int64) + timesteps += self.config.steps_offset + elif self.config.timestep_spacing == "trailing": + step_ratio = self.config.num_train_timesteps / num_inference_steps + # creates integer timesteps by multiplying by ratio + # casting to int to avoid issues when num_inference_step is power of 3 + timesteps = np.arange(self.config.num_train_timesteps, 0, -step_ratio).round().copy().astype(np.int64) + timesteps -= 1 + else: + raise ValueError( + f"{self.config.timestep_spacing} is not supported. Please make sure to choose one of 'linspace', 'leading' or 'trailing'." + ) + + sigmas = np.array(((1 - self.alphas_cumprod) / self.alphas_cumprod) ** 0.5) + if self.config.use_karras_sigmas: + log_sigmas = np.log(sigmas) + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_karras(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]).round() + if self.config.final_sigmas_type == "sigma_min": + sigma_last = sigmas[-1] + elif self.config.final_sigmas_type == "zero": + sigma_last = 0 + else: + raise ValueError( + f"`final_sigmas_type` must be one of 'zero', or 'sigma_min', but got {self.config.final_sigmas_type}" + ) + sigmas = np.concatenate([sigmas, [sigma_last]]).astype(np.float32) + elif self.config.use_exponential_sigmas: + log_sigmas = np.log(sigmas) + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_exponential(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + if self.config.final_sigmas_type == "sigma_min": + sigma_last = sigmas[-1] + elif self.config.final_sigmas_type == "zero": + sigma_last = 0 + else: + raise ValueError( + f"`final_sigmas_type` must be one of 'zero', or 'sigma_min', but got {self.config.final_sigmas_type}" + ) + sigmas = np.concatenate([sigmas, [sigma_last]]).astype(np.float32) + elif self.config.use_beta_sigmas: + log_sigmas = np.log(sigmas) + sigmas = np.flip(sigmas).copy() + sigmas = self._convert_to_beta(in_sigmas=sigmas, num_inference_steps=num_inference_steps) + timesteps = np.array([self._sigma_to_t(sigma, log_sigmas) for sigma in sigmas]) + if self.config.final_sigmas_type == "sigma_min": + sigma_last = sigmas[-1] + elif self.config.final_sigmas_type == "zero": + sigma_last = 0 + else: + raise ValueError( + f"`final_sigmas_type` must be one of 'zero', or 'sigma_min', but got {self.config.final_sigmas_type}" + ) + sigmas = np.concatenate([sigmas, [sigma_last]]).astype(np.float32) + elif self.config.use_flow_sigmas: + alphas = np.linspace(1, 1 / self.config.num_train_timesteps, num_inference_steps + 1) + sigmas = 1.0 - alphas + sigmas = np.flip(self.config.flow_shift * sigmas / (1 + (self.config.flow_shift - 1) * sigmas))[:-1].copy() + timesteps = (sigmas * self.config.num_train_timesteps).copy() + if self.config.final_sigmas_type == "sigma_min": + sigma_last = sigmas[-1] + elif self.config.final_sigmas_type == "zero": + sigma_last = 0 + else: + raise ValueError( + f"`final_sigmas_type` must be one of 'zero', or 'sigma_min', but got {self.config.final_sigmas_type}" + ) + sigmas = np.concatenate([sigmas, [sigma_last]]).astype(np.float32) + else: + sigmas = np.interp(timesteps, np.arange(0, len(sigmas)), sigmas) + if self.config.final_sigmas_type == "sigma_min": + sigma_last = ((1 - self.alphas_cumprod[0]) / self.alphas_cumprod[0]) ** 0.5 + elif self.config.final_sigmas_type == "zero": + sigma_last = 0 + else: + raise ValueError( + f"`final_sigmas_type` must be one of 'zero', or 'sigma_min', but got {self.config.final_sigmas_type}" + ) + sigmas = np.concatenate([sigmas, [sigma_last]]).astype(np.float32) + + self.sigmas = torch.from_numpy(sigmas) + self.timesteps = torch.from_numpy(timesteps).to(device=device, dtype=torch.int64) + + self.num_inference_steps = len(timesteps) + + self.model_outputs = [ + None, + ] * self.config.solver_order + self.lower_order_nums = 0 + self.last_sample = None + if self.solver_p: + self.solver_p.set_timesteps(self.num_inference_steps, device=device) + + # add an index counter for schedulers that allow duplicated timesteps + self._step_index = None + self._begin_index = None + self.sigmas = self.sigmas.to("cpu") # to avoid too much CPU/GPU communication + + # Copied from diffusers.schedulers.scheduling_ddpm.DDPMScheduler._threshold_sample + def _threshold_sample(self, sample: torch.Tensor) -> torch.Tensor: + """ + "Dynamic thresholding: At each sampling step we set s to a certain percentile absolute pixel value in xt0 (the + prediction of x_0 at timestep t), and if s > 1, then we threshold xt0 to the range [-s, s] and then divide by + s. Dynamic thresholding pushes saturated pixels (those near -1 and 1) inwards, thereby actively preventing + pixels from saturation at each step. We find that dynamic thresholding results in significantly better + photorealism as well as better image-text alignment, especially when using very large guidance weights." + + https://huggingface.co/papers/2205.11487 + """ + dtype = sample.dtype + batch_size, channels, *remaining_dims = sample.shape + + if dtype not in (torch.float32, torch.float64): + sample = sample.float() # upcast for quantile calculation, and clamp not implemented for cpu half + + # Flatten sample for doing quantile calculation along each image + sample = sample.reshape(batch_size, channels * np.prod(remaining_dims)) + + abs_sample = sample.abs() # "a certain percentile absolute pixel value" + + s = torch.quantile(abs_sample, self.config.dynamic_thresholding_ratio, dim=1) + s = torch.clamp( + s, min=1, max=self.config.sample_max_value + ) # When clamped to min=1, equivalent to standard clipping to [-1, 1] + s = s.unsqueeze(1) # (batch_size, 1) because clamp will broadcast along dim=0 + sample = torch.clamp(sample, -s, s) / s # "we threshold xt0 to the range [-s, s] and then divide by s" + + sample = sample.reshape(batch_size, channels, *remaining_dims) + sample = sample.to(dtype) + + return sample + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._sigma_to_t + def _sigma_to_t(self, sigma, log_sigmas): + # get log sigma + log_sigma = np.log(np.maximum(sigma, 1e-10)) + + # get distribution + dists = log_sigma - log_sigmas[:, np.newaxis] + + # get sigmas range + low_idx = np.cumsum((dists >= 0), axis=0).argmax(axis=0).clip(max=log_sigmas.shape[0] - 2) + high_idx = low_idx + 1 + + low = log_sigmas[low_idx] + high = log_sigmas[high_idx] + + # interpolate sigmas + w = (low - log_sigma) / (low - high) + w = np.clip(w, 0, 1) + + # transform interpolation to time range + t = (1 - w) * low_idx + w * high_idx + t = t.reshape(sigma.shape) + return t + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler._sigma_to_alpha_sigma_t + def _sigma_to_alpha_sigma_t(self, sigma): + if self.config.use_flow_sigmas: + alpha_t = 1 - sigma + sigma_t = sigma + else: + alpha_t = 1 / ((sigma**2 + 1) ** 0.5) + sigma_t = sigma * alpha_t + + return alpha_t, sigma_t + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_karras + def _convert_to_karras(self, in_sigmas: torch.Tensor, num_inference_steps) -> torch.Tensor: + """Constructs the noise schedule of Karras et al. (2022).""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + rho = 7.0 # 7.0 is the value used in the paper + ramp = np.linspace(0, 1, num_inference_steps) + min_inv_rho = sigma_min ** (1 / rho) + max_inv_rho = sigma_max ** (1 / rho) + sigmas = (max_inv_rho + ramp * (min_inv_rho - max_inv_rho)) ** rho + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_exponential + def _convert_to_exponential(self, in_sigmas: torch.Tensor, num_inference_steps: int) -> torch.Tensor: + """Constructs an exponential noise schedule.""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.exp(np.linspace(math.log(sigma_max), math.log(sigma_min), num_inference_steps)) + return sigmas + + # Copied from diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler._convert_to_beta + def _convert_to_beta( + self, in_sigmas: torch.Tensor, num_inference_steps: int, alpha: float = 0.6, beta: float = 0.6 + ) -> torch.Tensor: + """From "Beta Sampling is All You Need" [arXiv:2407.12173] (Lee et. al, 2024)""" + + # Hack to make sure that other schedulers which copy this function don't break + # TODO: Add this logic to the other schedulers + if hasattr(self.config, "sigma_min"): + sigma_min = self.config.sigma_min + else: + sigma_min = None + + if hasattr(self.config, "sigma_max"): + sigma_max = self.config.sigma_max + else: + sigma_max = None + + sigma_min = sigma_min if sigma_min is not None else in_sigmas[-1].item() + sigma_max = sigma_max if sigma_max is not None else in_sigmas[0].item() + + sigmas = np.array( + [ + sigma_min + (ppf * (sigma_max - sigma_min)) + for ppf in [ + scipy.stats.beta.ppf(timestep, alpha, beta) + for timestep in 1 - np.linspace(0, 1, num_inference_steps) + ] + ] + ) + return sigmas + + def convert_model_output( + self, + model_output: torch.Tensor, + *args, + sample: torch.Tensor = None, + **kwargs, + ) -> torch.Tensor: + r""" + Convert the model output to the corresponding type the UniPC algorithm needs. + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + + Returns: + `torch.Tensor`: + The converted model output. + """ + timestep = args[0] if len(args) > 0 else kwargs.pop("timestep", None) + if sample is None: + if len(args) > 1: + sample = args[1] + else: + raise ValueError("missing `sample` as a required keyword argument") + if timestep is not None: + deprecate( + "timesteps", + "1.0.0", + "Passing `timesteps` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + sigma = self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + + if self.predict_x0: + if self.config.prediction_type == "epsilon": + x0_pred = (sample - sigma_t * model_output) / alpha_t + elif self.config.prediction_type == "sample": + x0_pred = model_output + elif self.config.prediction_type == "v_prediction": + x0_pred = alpha_t * sample - sigma_t * model_output + elif self.config.prediction_type == "flow_prediction": + sigma_t = self.sigmas[self.step_index] + x0_pred = sample - sigma_t * model_output + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, " + "`v_prediction`, or `flow_prediction` for the UniPCMultistepScheduler." + ) + + if self.config.thresholding: + x0_pred = self._threshold_sample(x0_pred) + + return x0_pred + else: + if self.config.prediction_type == "epsilon": + return model_output + elif self.config.prediction_type == "sample": + epsilon = (sample - alpha_t * model_output) / sigma_t + return epsilon + elif self.config.prediction_type == "v_prediction": + epsilon = alpha_t * model_output + sigma_t * sample + return epsilon + else: + raise ValueError( + f"prediction_type given as {self.config.prediction_type} must be one of `epsilon`, `sample`, or" + " `v_prediction` for the UniPCMultistepScheduler." + ) + + def multistep_uni_p_bh_update( + self, + model_output: torch.Tensor, + *args, + sample: torch.Tensor = None, + order: int = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the UniP (B(h) version). Alternatively, `self.solver_p` is used if is specified. + + Args: + model_output (`torch.Tensor`): + The direct output from the learned diffusion model at the current timestep. + prev_timestep (`int`): + The previous discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + order (`int`): + The order of UniP at this timestep (corresponds to the *p* in UniPC-p). + + Returns: + `torch.Tensor`: + The sample tensor at the previous timestep. + """ + prev_timestep = args[0] if len(args) > 0 else kwargs.pop("prev_timestep", None) + if sample is None: + if len(args) > 1: + sample = args[1] + else: + raise ValueError("missing `sample` as a required keyword argument") + if order is None: + if len(args) > 2: + order = args[2] + else: + raise ValueError("missing `order` as a required keyword argument") + if prev_timestep is not None: + deprecate( + "prev_timestep", + "1.0.0", + "Passing `prev_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + model_output_list = self.model_outputs + + s0 = self.timestep_list[-1] + m0 = model_output_list[-1] + x = sample + + if self.solver_p: + x_t = self.solver_p.step(model_output, s0, x).prev_sample + return x_t + + sigma_t, sigma_s0 = self.sigmas[self.step_index + 1], self.sigmas[self.step_index] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s0 = torch.log(alpha_s0) - torch.log(sigma_s0) + + h = lambda_t - lambda_s0 + device = sample.device + + rks = [] + D1s = [] + for i in range(1, order): + si = self.step_index - i + mi = model_output_list[-(i + 1)] + alpha_si, sigma_si = self._sigma_to_alpha_sigma_t(self.sigmas[si]) + lambda_si = torch.log(alpha_si) - torch.log(sigma_si) + rk = (lambda_si - lambda_s0) / h + rks.append(rk) + D1s.append((mi - m0) / rk) + + rks.append(1.0) + rks = torch.tensor(rks, device=device) + + R = [] + b = [] + + hh = -h if self.predict_x0 else h + h_phi_1 = torch.expm1(hh) # h\phi_1(h) = e^h - 1 + h_phi_k = h_phi_1 / hh - 1 + + factorial_i = 1 + + if self.config.solver_type == "bh1": + B_h = hh + elif self.config.solver_type == "bh2": + B_h = torch.expm1(hh) + else: + raise NotImplementedError() + + for i in range(1, order + 1): + R.append(torch.pow(rks, i - 1)) + b.append(h_phi_k * factorial_i / B_h) + factorial_i *= i + 1 + h_phi_k = h_phi_k / hh - 1 / factorial_i + + R = torch.stack(R) + b = torch.tensor(b, device=device) + + if len(D1s) > 0: + D1s = torch.stack(D1s, dim=1) # (B, K) + # for order 2, we use a simplified version + if order == 2: + rhos_p = torch.tensor([0.5], dtype=x.dtype, device=device) + else: + rhos_p = torch.linalg.solve(R[:-1, :-1], b[:-1]).to(device).to(x.dtype) + else: + D1s = None + + if self.predict_x0: + x_t_ = sigma_t / sigma_s0 * x - alpha_t * h_phi_1 * m0 + if D1s is not None: + pred_res = torch.einsum("k,bkc...->bc...", rhos_p, D1s) + else: + pred_res = 0 + x_t = x_t_ - alpha_t * B_h * pred_res + else: + x_t_ = alpha_t / alpha_s0 * x - sigma_t * h_phi_1 * m0 + if D1s is not None: + pred_res = torch.einsum("k,bkc...->bc...", rhos_p, D1s) + else: + pred_res = 0 + x_t = x_t_ - sigma_t * B_h * pred_res + + x_t = x_t.to(x.dtype) + return x_t + + def multistep_uni_c_bh_update( + self, + this_model_output: torch.Tensor, + *args, + last_sample: torch.Tensor = None, + this_sample: torch.Tensor = None, + order: int = None, + **kwargs, + ) -> torch.Tensor: + """ + One step for the UniC (B(h) version). + + Args: + this_model_output (`torch.Tensor`): + The model outputs at `x_t`. + this_timestep (`int`): + The current timestep `t`. + last_sample (`torch.Tensor`): + The generated sample before the last predictor `x_{t-1}`. + this_sample (`torch.Tensor`): + The generated sample after the last predictor `x_{t}`. + order (`int`): + The `p` of UniC-p at this step. The effective order of accuracy should be `order + 1`. + + Returns: + `torch.Tensor`: + The corrected sample tensor at the current timestep. + """ + this_timestep = args[0] if len(args) > 0 else kwargs.pop("this_timestep", None) + if last_sample is None: + if len(args) > 1: + last_sample = args[1] + else: + raise ValueError("missing `last_sample` as a required keyword argument") + if this_sample is None: + if len(args) > 2: + this_sample = args[2] + else: + raise ValueError("missing `this_sample` as a required keyword argument") + if order is None: + if len(args) > 3: + order = args[3] + else: + raise ValueError("missing `order` as a required keyword argument") + if this_timestep is not None: + deprecate( + "this_timestep", + "1.0.0", + "Passing `this_timestep` is deprecated and has no effect as model output conversion is now handled via an internal counter `self.step_index`", + ) + + model_output_list = self.model_outputs + + m0 = model_output_list[-1] + x = last_sample + x_t = this_sample + model_t = this_model_output + + sigma_t, sigma_s0 = self.sigmas[self.step_index], self.sigmas[self.step_index - 1] + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma_t) + alpha_s0, sigma_s0 = self._sigma_to_alpha_sigma_t(sigma_s0) + + lambda_t = torch.log(alpha_t) - torch.log(sigma_t) + lambda_s0 = torch.log(alpha_s0) - torch.log(sigma_s0) + + h = lambda_t - lambda_s0 + device = this_sample.device + + rks = [] + D1s = [] + for i in range(1, order): + si = self.step_index - (i + 1) + mi = model_output_list[-(i + 1)] + alpha_si, sigma_si = self._sigma_to_alpha_sigma_t(self.sigmas[si]) + lambda_si = torch.log(alpha_si) - torch.log(sigma_si) + rk = (lambda_si - lambda_s0) / h + rks.append(rk) + D1s.append((mi - m0) / rk) + + rks.append(1.0) + rks = torch.tensor(rks, device=device) + + R = [] + b = [] + + hh = -h if self.predict_x0 else h + h_phi_1 = torch.expm1(hh) # h\phi_1(h) = e^h - 1 + h_phi_k = h_phi_1 / hh - 1 + + factorial_i = 1 + + if self.config.solver_type == "bh1": + B_h = hh + elif self.config.solver_type == "bh2": + B_h = torch.expm1(hh) + else: + raise NotImplementedError() + + for i in range(1, order + 1): + R.append(torch.pow(rks, i - 1)) + b.append(h_phi_k * factorial_i / B_h) + factorial_i *= i + 1 + h_phi_k = h_phi_k / hh - 1 / factorial_i + + R = torch.stack(R) + b = torch.tensor(b, device=device) + + if len(D1s) > 0: + D1s = torch.stack(D1s, dim=1) + else: + D1s = None + + # for order 1, we use a simplified version + if order == 1: + rhos_c = torch.tensor([0.5], dtype=x.dtype, device=device) + else: + rhos_c = torch.linalg.solve(R, b).to(device).to(x.dtype) + + if self.predict_x0: + x_t_ = sigma_t / sigma_s0 * x - alpha_t * h_phi_1 * m0 + if D1s is not None: + corr_res = torch.einsum("k,bkc...->bc...", rhos_c[:-1], D1s) + else: + corr_res = 0 + D1_t = model_t - m0 + x_t = x_t_ - alpha_t * B_h * (corr_res + rhos_c[-1] * D1_t) + else: + x_t_ = alpha_t / alpha_s0 * x - sigma_t * h_phi_1 * m0 + if D1s is not None: + corr_res = torch.einsum("k,bkc...->bc...", rhos_c[:-1], D1s) + else: + corr_res = 0 + D1_t = model_t - m0 + x_t = x_t_ - sigma_t * B_h * (corr_res + rhos_c[-1] * D1_t) + x_t = x_t.to(x.dtype) + return x_t + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.index_for_timestep + def index_for_timestep(self, timestep, schedule_timesteps=None): + if schedule_timesteps is None: + schedule_timesteps = self.timesteps + + index_candidates = (schedule_timesteps == timestep).nonzero() + + if len(index_candidates) == 0: + step_index = len(self.timesteps) - 1 + # The sigma index that is taken for the **very** first `step` + # is always the second index (or the last index if there is only 1) + # This way we can ensure we don't accidentally skip a sigma in + # case we start in the middle of the denoising schedule (e.g. for image-to-image) + elif len(index_candidates) > 1: + step_index = index_candidates[1].item() + else: + step_index = index_candidates[0].item() + + return step_index + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler._init_step_index + def _init_step_index(self, timestep): + """ + Initialize the step_index counter for the scheduler. + """ + + if self.begin_index is None: + if isinstance(timestep, torch.Tensor): + timestep = timestep.to(self.timesteps.device) + self._step_index = self.index_for_timestep(timestep) + else: + self._step_index = self._begin_index + + def step( + self, + model_output: torch.Tensor, + timestep: Union[int, torch.Tensor], + sample: torch.Tensor, + return_dict: bool = True, + ) -> Union[SchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by reversing the SDE. This function propagates the sample with + the multistep UniPC. + + Args: + model_output (`torch.Tensor`): + The direct output from learned diffusion model. + timestep (`int`): + The current discrete timestep in the diffusion chain. + sample (`torch.Tensor`): + A current instance of a sample created by the diffusion process. + return_dict (`bool`): + Whether or not to return a [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`. + + Returns: + [`~schedulers.scheduling_utils.SchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_utils.SchedulerOutput`] is returned, otherwise a + tuple is returned where the first element is the sample tensor. + + """ + if self.num_inference_steps is None: + raise ValueError( + "Number of inference steps is 'None', you need to run 'set_timesteps' after creating the scheduler" + ) + + if self.step_index is None: + self._init_step_index(timestep) + + use_corrector = ( + self.step_index > 0 and self.step_index - 1 not in self.disable_corrector and self.last_sample is not None + ) + + model_output_convert = self.convert_model_output(model_output, sample=sample) + if use_corrector: + sample = self.multistep_uni_c_bh_update( + this_model_output=model_output_convert, + last_sample=self.last_sample, + this_sample=sample, + order=self.this_order, + ) + + for i in range(self.config.solver_order - 1): + self.model_outputs[i] = self.model_outputs[i + 1] + self.timestep_list[i] = self.timestep_list[i + 1] + + self.model_outputs[-1] = model_output_convert + self.timestep_list[-1] = timestep + + if self.config.lower_order_final: + this_order = min(self.config.solver_order, len(self.timesteps) - self.step_index) + else: + this_order = self.config.solver_order + + self.this_order = min(this_order, self.lower_order_nums + 1) # warmup for multistep + assert self.this_order > 0 + + self.last_sample = sample + prev_sample = self.multistep_uni_p_bh_update( + model_output=model_output, # pass the original non-converted model output, in case solver-p is used + sample=sample, + order=self.this_order, + ) + + if self.lower_order_nums < self.config.solver_order: + self.lower_order_nums += 1 + + # upon completion increase step index by one + self._step_index += 1 + + if not return_dict: + return (prev_sample,) + + return SchedulerOutput(prev_sample=prev_sample) + + def scale_model_input(self, sample: torch.Tensor, *args, **kwargs) -> torch.Tensor: + """ + Ensures interchangeability with schedulers that need to scale the denoising model input depending on the + current timestep. + + Args: + sample (`torch.Tensor`): + The input sample. + + Returns: + `torch.Tensor`: + A scaled input sample. + """ + return sample + + # Copied from diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler.add_noise + def add_noise( + self, + original_samples: torch.Tensor, + noise: torch.Tensor, + timesteps: torch.IntTensor, + ) -> torch.Tensor: + # Make sure sigmas and timesteps have the same device and dtype as original_samples + sigmas = self.sigmas.to(device=original_samples.device, dtype=original_samples.dtype) + if original_samples.device.type == "mps" and torch.is_floating_point(timesteps): + # mps does not support float64 + schedule_timesteps = self.timesteps.to(original_samples.device, dtype=torch.float32) + timesteps = timesteps.to(original_samples.device, dtype=torch.float32) + else: + schedule_timesteps = self.timesteps.to(original_samples.device) + timesteps = timesteps.to(original_samples.device) + + # begin_index is None when the scheduler is used for training or pipeline does not implement set_begin_index + if self.begin_index is None: + step_indices = [self.index_for_timestep(t, schedule_timesteps) for t in timesteps] + elif self.step_index is not None: + # add_noise is called after first denoising step (for inpainting) + step_indices = [self.step_index] * timesteps.shape[0] + else: + # add noise is called before first denoising step to create initial latent(img2img) + step_indices = [self.begin_index] * timesteps.shape[0] + + sigma = sigmas[step_indices].flatten() + while len(sigma.shape) < len(original_samples.shape): + sigma = sigma.unsqueeze(-1) + + alpha_t, sigma_t = self._sigma_to_alpha_sigma_t(sigma) + noisy_samples = alpha_t * original_samples + sigma_t * noise + return noisy_samples + + def __len__(self): + return self.config.num_train_timesteps diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..83f31b72c10b8fad29a39db492caf2a2828cbdd2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_utils.py @@ -0,0 +1,194 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import importlib +import os +from dataclasses import dataclass +from enum import Enum +from typing import Optional, Union + +import torch +from huggingface_hub.utils import validate_hf_hub_args +from typing_extensions import Self + +from ..utils import BaseOutput, PushToHubMixin + + +SCHEDULER_CONFIG_NAME = "scheduler_config.json" + + +# NOTE: We make this type an enum because it simplifies usage in docs and prevents +# circular imports when used for `_compatibles` within the schedulers module. +# When it's used as a type in pipelines, it really is a Union because the actual +# scheduler instance is passed in. +class KarrasDiffusionSchedulers(Enum): + DDIMScheduler = 1 + DDPMScheduler = 2 + PNDMScheduler = 3 + LMSDiscreteScheduler = 4 + EulerDiscreteScheduler = 5 + HeunDiscreteScheduler = 6 + EulerAncestralDiscreteScheduler = 7 + DPMSolverMultistepScheduler = 8 + DPMSolverSinglestepScheduler = 9 + KDPM2DiscreteScheduler = 10 + KDPM2AncestralDiscreteScheduler = 11 + DEISMultistepScheduler = 12 + UniPCMultistepScheduler = 13 + DPMSolverSDEScheduler = 14 + EDMEulerScheduler = 15 + + +AysSchedules = { + "StableDiffusionTimesteps": [999, 850, 736, 645, 545, 455, 343, 233, 124, 24], + "StableDiffusionSigmas": [14.615, 6.475, 3.861, 2.697, 1.886, 1.396, 0.963, 0.652, 0.399, 0.152, 0.0], + "StableDiffusionXLTimesteps": [999, 845, 730, 587, 443, 310, 193, 116, 53, 13], + "StableDiffusionXLSigmas": [14.615, 6.315, 3.771, 2.181, 1.342, 0.862, 0.555, 0.380, 0.234, 0.113, 0.0], + "StableDiffusionVideoSigmas": [700.00, 54.5, 15.886, 7.977, 4.248, 1.789, 0.981, 0.403, 0.173, 0.034, 0.0], +} + + +@dataclass +class SchedulerOutput(BaseOutput): + """ + Base class for the output of a scheduler's `step` function. + + Args: + prev_sample (`torch.Tensor` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample `(x_{t-1})` of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + """ + + prev_sample: torch.Tensor + + +class SchedulerMixin(PushToHubMixin): + """ + Base class for all schedulers. + + [`SchedulerMixin`] contains common functions shared by all schedulers such as general loading and saving + functionalities. + + [`ConfigMixin`] takes care of storing the configuration attributes (like `num_train_timesteps`) that are passed to + the scheduler's `__init__` function, and the attributes can be accessed by `scheduler.config.num_train_timesteps`. + + Class attributes: + - **_compatibles** (`List[str]`) -- A list of scheduler classes that are compatible with the parent scheduler + class. Use [`~ConfigMixin.from_config`] to load a different compatible scheduler class (should be overridden + by parent class). + """ + + config_name = SCHEDULER_CONFIG_NAME + _compatibles = [] + has_compatibles = True + + @classmethod + @validate_hf_hub_args + def from_pretrained( + cls, + pretrained_model_name_or_path: Optional[Union[str, os.PathLike]] = None, + subfolder: Optional[str] = None, + return_unused_kwargs=False, + **kwargs, + ) -> Self: + r""" + Instantiate a scheduler from a pre-defined JSON configuration file in a local directory or Hub repository. + + Parameters: + pretrained_model_name_or_path (`str` or `os.PathLike`, *optional*): + Can be either: + + - A string, the *model id* (for example `google/ddpm-celebahq-256`) of a pretrained model hosted on + the Hub. + - A path to a *directory* (for example `./my_model_directory`) containing the scheduler + configuration saved with [`~SchedulerMixin.save_pretrained`]. + subfolder (`str`, *optional*): + The subfolder location of a model file within a larger model repository on the Hub or locally. + return_unused_kwargs (`bool`, *optional*, defaults to `False`): + Whether kwargs that are not consumed by the Python class should be returned or not. + cache_dir (`Union[str, os.PathLike]`, *optional*): + Path to a directory where a downloaded pretrained model configuration is cached if the standard cache + is not used. + force_download (`bool`, *optional*, defaults to `False`): + Whether or not to force the (re-)download of the model weights and configuration files, overriding the + cached versions if they exist. + + proxies (`Dict[str, str]`, *optional*): + A dictionary of proxy servers to use by protocol or endpoint, for example, `{'http': 'foo.bar:3128', + 'http://hostname': 'foo.bar:4012'}`. The proxies are used on each request. + output_loading_info(`bool`, *optional*, defaults to `False`): + Whether or not to also return a dictionary containing missing keys, unexpected keys and error messages. + local_files_only(`bool`, *optional*, defaults to `False`): + Whether to only load local model weights and configuration files or not. If set to `True`, the model + won't be downloaded from the Hub. + token (`str` or *bool*, *optional*): + The token to use as HTTP bearer authorization for remote files. If `True`, the token generated from + `diffusers-cli login` (stored in `~/.huggingface`) is used. + revision (`str`, *optional*, defaults to `"main"`): + The specific model version to use. It can be a branch name, a tag name, a commit id, or any identifier + allowed by Git. + + + + To use private or [gated models](https://huggingface.co/docs/hub/models-gated#gated-models), log-in with + `huggingface-cli login`. You can also activate the special + ["offline-mode"](https://huggingface.co/diffusers/installation.html#offline-mode) to use this method in a + firewalled environment. + + + + """ + config, kwargs, commit_hash = cls.load_config( + pretrained_model_name_or_path=pretrained_model_name_or_path, + subfolder=subfolder, + return_unused_kwargs=True, + return_commit_hash=True, + **kwargs, + ) + return cls.from_config(config, return_unused_kwargs=return_unused_kwargs, **kwargs) + + def save_pretrained(self, save_directory: Union[str, os.PathLike], push_to_hub: bool = False, **kwargs): + """ + Save a scheduler configuration object to a directory so that it can be reloaded using the + [`~SchedulerMixin.from_pretrained`] class method. + + Args: + save_directory (`str` or `os.PathLike`): + Directory where the configuration JSON file will be saved (will be created if it does not exist). + push_to_hub (`bool`, *optional*, defaults to `False`): + Whether or not to push your model to the Hugging Face Hub after saving it. You can specify the + repository you want to push to with `repo_id` (will default to the name of `save_directory` in your + namespace). + kwargs (`Dict[str, Any]`, *optional*): + Additional keyword arguments passed along to the [`~utils.PushToHubMixin.push_to_hub`] method. + """ + self.save_config(save_directory=save_directory, push_to_hub=push_to_hub, **kwargs) + + @property + def compatibles(self): + """ + Returns all schedulers that are compatible with this scheduler + + Returns: + `List[SchedulerMixin]`: List of compatible schedulers + """ + return self._get_compatibles() + + @classmethod + def _get_compatibles(cls): + compatible_classes_str = list(set([cls.__name__] + cls._compatibles)) + diffusers_library = importlib.import_module(__name__.split(".")[0]) + compatible_classes = [ + getattr(diffusers_library, c) for c in compatible_classes_str if hasattr(diffusers_library, c) + ] + return compatible_classes diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_utils_flax.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_utils_flax.py new file mode 100644 index 0000000000000000000000000000000000000000..ae11baf9ea1b4d3d0e67cb77ea7dc01eca1511bf --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_utils_flax.py @@ -0,0 +1,291 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import importlib +import math +import os +from dataclasses import dataclass +from enum import Enum +from typing import Optional, Tuple, Union + +import flax +import jax.numpy as jnp +from huggingface_hub.utils import validate_hf_hub_args + +from ..utils import BaseOutput, PushToHubMixin + + +SCHEDULER_CONFIG_NAME = "scheduler_config.json" + + +# NOTE: We make this type an enum because it simplifies usage in docs and prevents +# circular imports when used for `_compatibles` within the schedulers module. +# When it's used as a type in pipelines, it really is a Union because the actual +# scheduler instance is passed in. +class FlaxKarrasDiffusionSchedulers(Enum): + FlaxDDIMScheduler = 1 + FlaxDDPMScheduler = 2 + FlaxPNDMScheduler = 3 + FlaxLMSDiscreteScheduler = 4 + FlaxDPMSolverMultistepScheduler = 5 + FlaxEulerDiscreteScheduler = 6 + + +@dataclass +class FlaxSchedulerOutput(BaseOutput): + """ + Base class for the scheduler's step function output. + + Args: + prev_sample (`jnp.ndarray` of shape `(batch_size, num_channels, height, width)` for images): + Computed sample (x_{t-1}) of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + """ + + prev_sample: jnp.ndarray + + +class FlaxSchedulerMixin(PushToHubMixin): + """ + Mixin containing common functions for the schedulers. + + Class attributes: + - **_compatibles** (`List[str]`) -- A list of classes that are compatible with the parent class, so that + `from_config` can be used from a class different than the one used to save the config (should be overridden + by parent class). + """ + + config_name = SCHEDULER_CONFIG_NAME + ignore_for_config = ["dtype"] + _compatibles = [] + has_compatibles = True + + @classmethod + @validate_hf_hub_args + def from_pretrained( + cls, + pretrained_model_name_or_path: Optional[Union[str, os.PathLike]] = None, + subfolder: Optional[str] = None, + return_unused_kwargs=False, + **kwargs, + ): + r""" + Instantiate a Scheduler class from a pre-defined JSON-file. + + Parameters: + pretrained_model_name_or_path (`str` or `os.PathLike`, *optional*): + Can be either: + + - A string, the *model id* of a model repo on huggingface.co. Valid model ids should have an + organization name, like `google/ddpm-celebahq-256`. + - A path to a *directory* containing model weights saved using [`~SchedulerMixin.save_pretrained`], + e.g., `./my_model_directory/`. + subfolder (`str`, *optional*): + In case the relevant files are located inside a subfolder of the model repo (either remote in + huggingface.co or downloaded locally), you can specify the folder name here. + return_unused_kwargs (`bool`, *optional*, defaults to `False`): + Whether kwargs that are not consumed by the Python class should be returned or not. + + cache_dir (`Union[str, os.PathLike]`, *optional*): + Path to a directory in which a downloaded pretrained model configuration should be cached if the + standard cache should not be used. + force_download (`bool`, *optional*, defaults to `False`): + Whether or not to force the (re-)download of the model weights and configuration files, overriding the + cached versions if they exist. + + proxies (`Dict[str, str]`, *optional*): + A dictionary of proxy servers to use by protocol or endpoint, e.g., `{'http': 'foo.bar:3128', + 'http://hostname': 'foo.bar:4012'}`. The proxies are used on each request. + output_loading_info(`bool`, *optional*, defaults to `False`): + Whether or not to also return a dictionary containing missing keys, unexpected keys and error messages. + local_files_only(`bool`, *optional*, defaults to `False`): + Whether or not to only look at local files (i.e., do not try to download the model). + token (`str` or *bool*, *optional*): + The token to use as HTTP bearer authorization for remote files. If `True`, will use the token generated + when running `transformers-cli login` (stored in `~/.huggingface`). + revision (`str`, *optional*, defaults to `"main"`): + The specific model version to use. It can be a branch name, a tag name, or a commit id, since we use a + git-based system for storing models and other artifacts on huggingface.co, so `revision` can be any + identifier allowed by git. + + + + It is required to be logged in (`huggingface-cli login`) when you want to use private or [gated + models](https://huggingface.co/docs/hub/models-gated#gated-models). + + + + + + Activate the special ["offline-mode"](https://huggingface.co/transformers/installation.html#offline-mode) to + use this method in a firewalled environment. + + + + """ + config, kwargs = cls.load_config( + pretrained_model_name_or_path=pretrained_model_name_or_path, + subfolder=subfolder, + return_unused_kwargs=True, + **kwargs, + ) + scheduler, unused_kwargs = cls.from_config(config, return_unused_kwargs=True, **kwargs) + + if hasattr(scheduler, "create_state") and getattr(scheduler, "has_state", False): + state = scheduler.create_state() + + if return_unused_kwargs: + return scheduler, state, unused_kwargs + + return scheduler, state + + def save_pretrained(self, save_directory: Union[str, os.PathLike], push_to_hub: bool = False, **kwargs): + """ + Save a scheduler configuration object to the directory `save_directory`, so that it can be re-loaded using the + [`~FlaxSchedulerMixin.from_pretrained`] class method. + + Args: + save_directory (`str` or `os.PathLike`): + Directory where the configuration JSON file will be saved (will be created if it does not exist). + push_to_hub (`bool`, *optional*, defaults to `False`): + Whether or not to push your model to the Hugging Face Hub after saving it. You can specify the + repository you want to push to with `repo_id` (will default to the name of `save_directory` in your + namespace). + kwargs (`Dict[str, Any]`, *optional*): + Additional keyword arguments passed along to the [`~utils.PushToHubMixin.push_to_hub`] method. + """ + self.save_config(save_directory=save_directory, push_to_hub=push_to_hub, **kwargs) + + @property + def compatibles(self): + """ + Returns all schedulers that are compatible with this scheduler + + Returns: + `List[SchedulerMixin]`: List of compatible schedulers + """ + return self._get_compatibles() + + @classmethod + def _get_compatibles(cls): + compatible_classes_str = list(set([cls.__name__] + cls._compatibles)) + diffusers_library = importlib.import_module(__name__.split(".")[0]) + compatible_classes = [ + getattr(diffusers_library, c) for c in compatible_classes_str if hasattr(diffusers_library, c) + ] + return compatible_classes + + +def broadcast_to_shape_from_left(x: jnp.ndarray, shape: Tuple[int]) -> jnp.ndarray: + assert len(shape) >= x.ndim + return jnp.broadcast_to(x.reshape(x.shape + (1,) * (len(shape) - x.ndim)), shape) + + +def betas_for_alpha_bar(num_diffusion_timesteps: int, max_beta=0.999, dtype=jnp.float32) -> jnp.ndarray: + """ + Create a beta schedule that discretizes the given alpha_t_bar function, which defines the cumulative product of + (1-beta) over time from t = [0,1]. + + Contains a function alpha_bar that takes an argument t and transforms it to the cumulative product of (1-beta) up + to that part of the diffusion process. + + + Args: + num_diffusion_timesteps (`int`): the number of betas to produce. + max_beta (`float`): the maximum beta to use; use values lower than 1 to + prevent singularities. + + Returns: + betas (`jnp.ndarray`): the betas used by the scheduler to step the model outputs + """ + + def alpha_bar(time_step): + return math.cos((time_step + 0.008) / 1.008 * math.pi / 2) ** 2 + + betas = [] + for i in range(num_diffusion_timesteps): + t1 = i / num_diffusion_timesteps + t2 = (i + 1) / num_diffusion_timesteps + betas.append(min(1 - alpha_bar(t2) / alpha_bar(t1), max_beta)) + return jnp.array(betas, dtype=dtype) + + +@flax.struct.dataclass +class CommonSchedulerState: + alphas: jnp.ndarray + betas: jnp.ndarray + alphas_cumprod: jnp.ndarray + + @classmethod + def create(cls, scheduler): + config = scheduler.config + + if config.trained_betas is not None: + betas = jnp.asarray(config.trained_betas, dtype=scheduler.dtype) + elif config.beta_schedule == "linear": + betas = jnp.linspace(config.beta_start, config.beta_end, config.num_train_timesteps, dtype=scheduler.dtype) + elif config.beta_schedule == "scaled_linear": + # this schedule is very specific to the latent diffusion model. + betas = ( + jnp.linspace( + config.beta_start**0.5, config.beta_end**0.5, config.num_train_timesteps, dtype=scheduler.dtype + ) + ** 2 + ) + elif config.beta_schedule == "squaredcos_cap_v2": + # Glide cosine schedule + betas = betas_for_alpha_bar(config.num_train_timesteps, dtype=scheduler.dtype) + else: + raise NotImplementedError( + f"beta_schedule {config.beta_schedule} is not implemented for scheduler {scheduler.__class__.__name__}" + ) + + alphas = 1.0 - betas + + alphas_cumprod = jnp.cumprod(alphas, axis=0) + + return cls( + alphas=alphas, + betas=betas, + alphas_cumprod=alphas_cumprod, + ) + + +def get_sqrt_alpha_prod( + state: CommonSchedulerState, original_samples: jnp.ndarray, noise: jnp.ndarray, timesteps: jnp.ndarray +): + alphas_cumprod = state.alphas_cumprod + + sqrt_alpha_prod = alphas_cumprod[timesteps] ** 0.5 + sqrt_alpha_prod = sqrt_alpha_prod.flatten() + sqrt_alpha_prod = broadcast_to_shape_from_left(sqrt_alpha_prod, original_samples.shape) + + sqrt_one_minus_alpha_prod = (1 - alphas_cumprod[timesteps]) ** 0.5 + sqrt_one_minus_alpha_prod = sqrt_one_minus_alpha_prod.flatten() + sqrt_one_minus_alpha_prod = broadcast_to_shape_from_left(sqrt_one_minus_alpha_prod, original_samples.shape) + + return sqrt_alpha_prod, sqrt_one_minus_alpha_prod + + +def add_noise_common( + state: CommonSchedulerState, original_samples: jnp.ndarray, noise: jnp.ndarray, timesteps: jnp.ndarray +): + sqrt_alpha_prod, sqrt_one_minus_alpha_prod = get_sqrt_alpha_prod(state, original_samples, noise, timesteps) + noisy_samples = sqrt_alpha_prod * original_samples + sqrt_one_minus_alpha_prod * noise + return noisy_samples + + +def get_velocity_common(state: CommonSchedulerState, sample: jnp.ndarray, noise: jnp.ndarray, timesteps: jnp.ndarray): + sqrt_alpha_prod, sqrt_one_minus_alpha_prod = get_sqrt_alpha_prod(state, sample, noise, timesteps) + velocity = sqrt_alpha_prod * noise - sqrt_one_minus_alpha_prod * sample + return velocity diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_vq_diffusion.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_vq_diffusion.py new file mode 100644 index 0000000000000000000000000000000000000000..bd8d255fa9016621a4ffa03f39e019983c643445 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/schedulers/scheduling_vq_diffusion.py @@ -0,0 +1,467 @@ +# Copyright 2024 Microsoft and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +from dataclasses import dataclass +from typing import Optional, Tuple, Union + +import numpy as np +import torch +import torch.nn.functional as F + +from ..configuration_utils import ConfigMixin, register_to_config +from ..utils import BaseOutput +from .scheduling_utils import SchedulerMixin + + +@dataclass +class VQDiffusionSchedulerOutput(BaseOutput): + """ + Output class for the scheduler's step function output. + + Args: + prev_sample (`torch.LongTensor` of shape `(batch size, num latent pixels)`): + Computed sample x_{t-1} of previous timestep. `prev_sample` should be used as next model input in the + denoising loop. + """ + + prev_sample: torch.LongTensor + + +def index_to_log_onehot(x: torch.LongTensor, num_classes: int) -> torch.Tensor: + """ + Convert batch of vector of class indices into batch of log onehot vectors + + Args: + x (`torch.LongTensor` of shape `(batch size, vector length)`): + Batch of class indices + + num_classes (`int`): + number of classes to be used for the onehot vectors + + Returns: + `torch.Tensor` of shape `(batch size, num classes, vector length)`: + Log onehot vectors + """ + x_onehot = F.one_hot(x, num_classes) + x_onehot = x_onehot.permute(0, 2, 1) + log_x = torch.log(x_onehot.float().clamp(min=1e-30)) + return log_x + + +def gumbel_noised(logits: torch.Tensor, generator: Optional[torch.Generator]) -> torch.Tensor: + """ + Apply gumbel noise to `logits` + """ + uniform = torch.rand(logits.shape, device=logits.device, generator=generator) + gumbel_noise = -torch.log(-torch.log(uniform + 1e-30) + 1e-30) + noised = gumbel_noise + logits + return noised + + +def alpha_schedules(num_diffusion_timesteps: int, alpha_cum_start=0.99999, alpha_cum_end=0.000009): + """ + Cumulative and non-cumulative alpha schedules. + + See section 4.1. + """ + att = ( + np.arange(0, num_diffusion_timesteps) / (num_diffusion_timesteps - 1) * (alpha_cum_end - alpha_cum_start) + + alpha_cum_start + ) + att = np.concatenate(([1], att)) + at = att[1:] / att[:-1] + att = np.concatenate((att[1:], [1])) + return at, att + + +def gamma_schedules(num_diffusion_timesteps: int, gamma_cum_start=0.000009, gamma_cum_end=0.99999): + """ + Cumulative and non-cumulative gamma schedules. + + See section 4.1. + """ + ctt = ( + np.arange(0, num_diffusion_timesteps) / (num_diffusion_timesteps - 1) * (gamma_cum_end - gamma_cum_start) + + gamma_cum_start + ) + ctt = np.concatenate(([0], ctt)) + one_minus_ctt = 1 - ctt + one_minus_ct = one_minus_ctt[1:] / one_minus_ctt[:-1] + ct = 1 - one_minus_ct + ctt = np.concatenate((ctt[1:], [0])) + return ct, ctt + + +class VQDiffusionScheduler(SchedulerMixin, ConfigMixin): + """ + A scheduler for vector quantized diffusion. + + This model inherits from [`SchedulerMixin`] and [`ConfigMixin`]. Check the superclass documentation for the generic + methods the library implements for all schedulers such as loading and saving. + + Args: + num_vec_classes (`int`): + The number of classes of the vector embeddings of the latent pixels. Includes the class for the masked + latent pixel. + num_train_timesteps (`int`, defaults to 100): + The number of diffusion steps to train the model. + alpha_cum_start (`float`, defaults to 0.99999): + The starting cumulative alpha value. + alpha_cum_end (`float`, defaults to 0.00009): + The ending cumulative alpha value. + gamma_cum_start (`float`, defaults to 0.00009): + The starting cumulative gamma value. + gamma_cum_end (`float`, defaults to 0.99999): + The ending cumulative gamma value. + """ + + order = 1 + + @register_to_config + def __init__( + self, + num_vec_classes: int, + num_train_timesteps: int = 100, + alpha_cum_start: float = 0.99999, + alpha_cum_end: float = 0.000009, + gamma_cum_start: float = 0.000009, + gamma_cum_end: float = 0.99999, + ): + self.num_embed = num_vec_classes + + # By convention, the index for the mask class is the last class index + self.mask_class = self.num_embed - 1 + + at, att = alpha_schedules(num_train_timesteps, alpha_cum_start=alpha_cum_start, alpha_cum_end=alpha_cum_end) + ct, ctt = gamma_schedules(num_train_timesteps, gamma_cum_start=gamma_cum_start, gamma_cum_end=gamma_cum_end) + + num_non_mask_classes = self.num_embed - 1 + bt = (1 - at - ct) / num_non_mask_classes + btt = (1 - att - ctt) / num_non_mask_classes + + at = torch.tensor(at.astype("float64")) + bt = torch.tensor(bt.astype("float64")) + ct = torch.tensor(ct.astype("float64")) + log_at = torch.log(at) + log_bt = torch.log(bt) + log_ct = torch.log(ct) + + att = torch.tensor(att.astype("float64")) + btt = torch.tensor(btt.astype("float64")) + ctt = torch.tensor(ctt.astype("float64")) + log_cumprod_at = torch.log(att) + log_cumprod_bt = torch.log(btt) + log_cumprod_ct = torch.log(ctt) + + self.log_at = log_at.float() + self.log_bt = log_bt.float() + self.log_ct = log_ct.float() + self.log_cumprod_at = log_cumprod_at.float() + self.log_cumprod_bt = log_cumprod_bt.float() + self.log_cumprod_ct = log_cumprod_ct.float() + + # setable values + self.num_inference_steps = None + self.timesteps = torch.from_numpy(np.arange(0, num_train_timesteps)[::-1].copy()) + + def set_timesteps(self, num_inference_steps: int, device: Union[str, torch.device] = None): + """ + Sets the discrete timesteps used for the diffusion chain (to be run before inference). + + Args: + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps and diffusion process parameters (alpha, beta, gamma) should be moved + to. + """ + self.num_inference_steps = num_inference_steps + timesteps = np.arange(0, self.num_inference_steps)[::-1].copy() + self.timesteps = torch.from_numpy(timesteps).to(device) + + self.log_at = self.log_at.to(device) + self.log_bt = self.log_bt.to(device) + self.log_ct = self.log_ct.to(device) + self.log_cumprod_at = self.log_cumprod_at.to(device) + self.log_cumprod_bt = self.log_cumprod_bt.to(device) + self.log_cumprod_ct = self.log_cumprod_ct.to(device) + + def step( + self, + model_output: torch.Tensor, + timestep: torch.long, + sample: torch.LongTensor, + generator: Optional[torch.Generator] = None, + return_dict: bool = True, + ) -> Union[VQDiffusionSchedulerOutput, Tuple]: + """ + Predict the sample from the previous timestep by the reverse transition distribution. See + [`~VQDiffusionScheduler.q_posterior`] for more details about how the distribution is computer. + + Args: + log_p_x_0: (`torch.Tensor` of shape `(batch size, num classes - 1, num latent pixels)`): + The log probabilities for the predicted classes of the initial latent pixels. Does not include a + prediction for the masked class as the initial unnoised image cannot be masked. + t (`torch.long`): + The timestep that determines which transition matrices are used. + x_t (`torch.LongTensor` of shape `(batch size, num latent pixels)`): + The classes of each latent pixel at time `t`. + generator (`torch.Generator`, or `None`): + A random number generator for the noise applied to `p(x_{t-1} | x_t)` before it is sampled from. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~schedulers.scheduling_vq_diffusion.VQDiffusionSchedulerOutput`] or + `tuple`. + + Returns: + [`~schedulers.scheduling_vq_diffusion.VQDiffusionSchedulerOutput`] or `tuple`: + If return_dict is `True`, [`~schedulers.scheduling_vq_diffusion.VQDiffusionSchedulerOutput`] is + returned, otherwise a tuple is returned where the first element is the sample tensor. + """ + if timestep == 0: + log_p_x_t_min_1 = model_output + else: + log_p_x_t_min_1 = self.q_posterior(model_output, sample, timestep) + + log_p_x_t_min_1 = gumbel_noised(log_p_x_t_min_1, generator) + + x_t_min_1 = log_p_x_t_min_1.argmax(dim=1) + + if not return_dict: + return (x_t_min_1,) + + return VQDiffusionSchedulerOutput(prev_sample=x_t_min_1) + + def q_posterior(self, log_p_x_0, x_t, t): + """ + Calculates the log probabilities for the predicted classes of the image at timestep `t-1`: + + ``` + p(x_{t-1} | x_t) = sum( q(x_t | x_{t-1}) * q(x_{t-1} | x_0) * p(x_0) / q(x_t | x_0) ) + ``` + + Args: + log_p_x_0 (`torch.Tensor` of shape `(batch size, num classes - 1, num latent pixels)`): + The log probabilities for the predicted classes of the initial latent pixels. Does not include a + prediction for the masked class as the initial unnoised image cannot be masked. + x_t (`torch.LongTensor` of shape `(batch size, num latent pixels)`): + The classes of each latent pixel at time `t`. + t (`torch.Long`): + The timestep that determines which transition matrix is used. + + Returns: + `torch.Tensor` of shape `(batch size, num classes, num latent pixels)`: + The log probabilities for the predicted classes of the image at timestep `t-1`. + """ + log_onehot_x_t = index_to_log_onehot(x_t, self.num_embed) + + log_q_x_t_given_x_0 = self.log_Q_t_transitioning_to_known_class( + t=t, x_t=x_t, log_onehot_x_t=log_onehot_x_t, cumulative=True + ) + + log_q_t_given_x_t_min_1 = self.log_Q_t_transitioning_to_known_class( + t=t, x_t=x_t, log_onehot_x_t=log_onehot_x_t, cumulative=False + ) + + # p_0(x_0=C_0 | x_t) / q(x_t | x_0=C_0) ... p_n(x_0=C_0 | x_t) / q(x_t | x_0=C_0) + # . . . + # . . . + # . . . + # p_0(x_0=C_{k-1} | x_t) / q(x_t | x_0=C_{k-1}) ... p_n(x_0=C_{k-1} | x_t) / q(x_t | x_0=C_{k-1}) + q = log_p_x_0 - log_q_x_t_given_x_0 + + # sum_0 = p_0(x_0=C_0 | x_t) / q(x_t | x_0=C_0) + ... + p_0(x_0=C_{k-1} | x_t) / q(x_t | x_0=C_{k-1}), ... , + # sum_n = p_n(x_0=C_0 | x_t) / q(x_t | x_0=C_0) + ... + p_n(x_0=C_{k-1} | x_t) / q(x_t | x_0=C_{k-1}) + q_log_sum_exp = torch.logsumexp(q, dim=1, keepdim=True) + + # p_0(x_0=C_0 | x_t) / q(x_t | x_0=C_0) / sum_0 ... p_n(x_0=C_0 | x_t) / q(x_t | x_0=C_0) / sum_n + # . . . + # . . . + # . . . + # p_0(x_0=C_{k-1} | x_t) / q(x_t | x_0=C_{k-1}) / sum_0 ... p_n(x_0=C_{k-1} | x_t) / q(x_t | x_0=C_{k-1}) / sum_n + q = q - q_log_sum_exp + + # (p_0(x_0=C_0 | x_t) / q(x_t | x_0=C_0) / sum_0) * a_cumulative_{t-1} + b_cumulative_{t-1} ... (p_n(x_0=C_0 | x_t) / q(x_t | x_0=C_0) / sum_n) * a_cumulative_{t-1} + b_cumulative_{t-1} + # . . . + # . . . + # . . . + # (p_0(x_0=C_{k-1} | x_t) / q(x_t | x_0=C_{k-1}) / sum_0) * a_cumulative_{t-1} + b_cumulative_{t-1} ... (p_n(x_0=C_{k-1} | x_t) / q(x_t | x_0=C_{k-1}) / sum_n) * a_cumulative_{t-1} + b_cumulative_{t-1} + # c_cumulative_{t-1} ... c_cumulative_{t-1} + q = self.apply_cumulative_transitions(q, t - 1) + + # ((p_0(x_0=C_0 | x_t) / q(x_t | x_0=C_0) / sum_0) * a_cumulative_{t-1} + b_cumulative_{t-1}) * q(x_t | x_{t-1}=C_0) * sum_0 ... ((p_n(x_0=C_0 | x_t) / q(x_t | x_0=C_0) / sum_n) * a_cumulative_{t-1} + b_cumulative_{t-1}) * q(x_t | x_{t-1}=C_0) * sum_n + # . . . + # . . . + # . . . + # ((p_0(x_0=C_{k-1} | x_t) / q(x_t | x_0=C_{k-1}) / sum_0) * a_cumulative_{t-1} + b_cumulative_{t-1}) * q(x_t | x_{t-1}=C_{k-1}) * sum_0 ... ((p_n(x_0=C_{k-1} | x_t) / q(x_t | x_0=C_{k-1}) / sum_n) * a_cumulative_{t-1} + b_cumulative_{t-1}) * q(x_t | x_{t-1}=C_{k-1}) * sum_n + # c_cumulative_{t-1} * q(x_t | x_{t-1}=C_k) * sum_0 ... c_cumulative_{t-1} * q(x_t | x_{t-1}=C_k) * sum_0 + log_p_x_t_min_1 = q + log_q_t_given_x_t_min_1 + q_log_sum_exp + + # For each column, there are two possible cases. + # + # Where: + # - sum(p_n(x_0))) is summing over all classes for x_0 + # - C_i is the class transitioning from (not to be confused with c_t and c_cumulative_t being used for gamma's) + # - C_j is the class transitioning to + # + # 1. x_t is masked i.e. x_t = c_k + # + # Simplifying the expression, the column vector is: + # . + # . + # . + # (c_t / c_cumulative_t) * (a_cumulative_{t-1} * p_n(x_0 = C_i | x_t) + b_cumulative_{t-1} * sum(p_n(x_0))) + # . + # . + # . + # (c_cumulative_{t-1} / c_cumulative_t) * sum(p_n(x_0)) + # + # From equation (11) stated in terms of forward probabilities, the last row is trivially verified. + # + # For the other rows, we can state the equation as ... + # + # (c_t / c_cumulative_t) * [b_cumulative_{t-1} * p(x_0=c_0) + ... + (a_cumulative_{t-1} + b_cumulative_{t-1}) * p(x_0=C_i) + ... + b_cumulative_{k-1} * p(x_0=c_{k-1})] + # + # This verifies the other rows. + # + # 2. x_t is not masked + # + # Simplifying the expression, there are two cases for the rows of the column vector, where C_j = C_i and where C_j != C_i: + # . + # . + # . + # C_j != C_i: b_t * ((b_cumulative_{t-1} / b_cumulative_t) * p_n(x_0 = c_0) + ... + ((a_cumulative_{t-1} + b_cumulative_{t-1}) / b_cumulative_t) * p_n(x_0 = C_i) + ... + (b_cumulative_{t-1} / (a_cumulative_t + b_cumulative_t)) * p_n(c_0=C_j) + ... + (b_cumulative_{t-1} / b_cumulative_t) * p_n(x_0 = c_{k-1})) + # . + # . + # . + # C_j = C_i: (a_t + b_t) * ((b_cumulative_{t-1} / b_cumulative_t) * p_n(x_0 = c_0) + ... + ((a_cumulative_{t-1} + b_cumulative_{t-1}) / (a_cumulative_t + b_cumulative_t)) * p_n(x_0 = C_i = C_j) + ... + (b_cumulative_{t-1} / b_cumulative_t) * p_n(x_0 = c_{k-1})) + # . + # . + # . + # 0 + # + # The last row is trivially verified. The other rows can be verified by directly expanding equation (11) stated in terms of forward probabilities. + return log_p_x_t_min_1 + + def log_Q_t_transitioning_to_known_class( + self, *, t: torch.int, x_t: torch.LongTensor, log_onehot_x_t: torch.Tensor, cumulative: bool + ): + """ + Calculates the log probabilities of the rows from the (cumulative or non-cumulative) transition matrix for each + latent pixel in `x_t`. + + Args: + t (`torch.Long`): + The timestep that determines which transition matrix is used. + x_t (`torch.LongTensor` of shape `(batch size, num latent pixels)`): + The classes of each latent pixel at time `t`. + log_onehot_x_t (`torch.Tensor` of shape `(batch size, num classes, num latent pixels)`): + The log one-hot vectors of `x_t`. + cumulative (`bool`): + If cumulative is `False`, the single step transition matrix `t-1`->`t` is used. If cumulative is + `True`, the cumulative transition matrix `0`->`t` is used. + + Returns: + `torch.Tensor` of shape `(batch size, num classes - 1, num latent pixels)`: + Each _column_ of the returned matrix is a _row_ of log probabilities of the complete probability + transition matrix. + + When non cumulative, returns `self.num_classes - 1` rows because the initial latent pixel cannot be + masked. + + Where: + - `q_n` is the probability distribution for the forward process of the `n`th latent pixel. + - C_0 is a class of a latent pixel embedding + - C_k is the class of the masked latent pixel + + non-cumulative result (omitting logarithms): + ``` + q_0(x_t | x_{t-1} = C_0) ... q_n(x_t | x_{t-1} = C_0) + . . . + . . . + . . . + q_0(x_t | x_{t-1} = C_k) ... q_n(x_t | x_{t-1} = C_k) + ``` + + cumulative result (omitting logarithms): + ``` + q_0_cumulative(x_t | x_0 = C_0) ... q_n_cumulative(x_t | x_0 = C_0) + . . . + . . . + . . . + q_0_cumulative(x_t | x_0 = C_{k-1}) ... q_n_cumulative(x_t | x_0 = C_{k-1}) + ``` + """ + if cumulative: + a = self.log_cumprod_at[t] + b = self.log_cumprod_bt[t] + c = self.log_cumprod_ct[t] + else: + a = self.log_at[t] + b = self.log_bt[t] + c = self.log_ct[t] + + if not cumulative: + # The values in the onehot vector can also be used as the logprobs for transitioning + # from masked latent pixels. If we are not calculating the cumulative transitions, + # we need to save these vectors to be re-appended to the final matrix so the values + # aren't overwritten. + # + # `P(x_t!=mask|x_{t-1=mask}) = 0` and 0 will be the value of the last row of the onehot vector + # if x_t is not masked + # + # `P(x_t=mask|x_{t-1=mask}) = 1` and 1 will be the value of the last row of the onehot vector + # if x_t is masked + log_onehot_x_t_transitioning_from_masked = log_onehot_x_t[:, -1, :].unsqueeze(1) + + # `index_to_log_onehot` will add onehot vectors for masked pixels, + # so the default one hot matrix has one too many rows. See the doc string + # for an explanation of the dimensionality of the returned matrix. + log_onehot_x_t = log_onehot_x_t[:, :-1, :] + + # this is a cheeky trick to produce the transition probabilities using log one-hot vectors. + # + # Don't worry about what values this sets in the columns that mark transitions + # to masked latent pixels. They are overwrote later with the `mask_class_mask`. + # + # Looking at the below logspace formula in non-logspace, each value will evaluate to either + # `1 * a + b = a + b` where `log_Q_t` has the one hot value in the column + # or + # `0 * a + b = b` where `log_Q_t` has the 0 values in the column. + # + # See equation 7 for more details. + log_Q_t = (log_onehot_x_t + a).logaddexp(b) + + # The whole column of each masked pixel is `c` + mask_class_mask = x_t == self.mask_class + mask_class_mask = mask_class_mask.unsqueeze(1).expand(-1, self.num_embed - 1, -1) + log_Q_t[mask_class_mask] = c + + if not cumulative: + log_Q_t = torch.cat((log_Q_t, log_onehot_x_t_transitioning_from_masked), dim=1) + + return log_Q_t + + def apply_cumulative_transitions(self, q, t): + bsz = q.shape[0] + a = self.log_cumprod_at[t] + b = self.log_cumprod_bt[t] + c = self.log_cumprod_ct[t] + + num_latent_pixels = q.shape[2] + c = c.expand(bsz, 1, num_latent_pixels) + + q = (q + a).logaddexp(b) + q = torch.cat((q, c), dim=1) + + return q diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/training_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/training_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..43bf0010d7b3cc525267d335e14627920437ba73 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/training_utils.py @@ -0,0 +1,644 @@ +import contextlib +import copy +import gc +import math +import random +from typing import Any, Dict, Iterable, List, Optional, Tuple, Union + +import numpy as np +import torch + +from .models import UNet2DConditionModel +from .schedulers import SchedulerMixin +from .utils import ( + convert_state_dict_to_diffusers, + convert_state_dict_to_peft, + deprecate, + is_peft_available, + is_torch_npu_available, + is_torchvision_available, + is_transformers_available, +) + + +if is_transformers_available(): + import transformers + + if transformers.integrations.deepspeed.is_deepspeed_zero3_enabled(): + import deepspeed + +if is_peft_available(): + from peft import set_peft_model_state_dict + +if is_torchvision_available(): + from torchvision import transforms + +if is_torch_npu_available(): + import torch_npu # noqa: F401 + + +def set_seed(seed: int): + """ + Helper function for reproducible behavior to set the seed in `random`, `numpy`, `torch`. + + Args: + seed (`int`): The seed to set. + + Returns: + `None` + """ + random.seed(seed) + np.random.seed(seed) + torch.manual_seed(seed) + if is_torch_npu_available(): + torch.npu.manual_seed_all(seed) + else: + torch.cuda.manual_seed_all(seed) + # ^^ safe to call this function even if cuda is not available + + +def compute_snr(noise_scheduler, timesteps): + """ + Computes SNR as per + https://github.com/TiankaiHang/Min-SNR-Diffusion-Training/blob/521b624bd70c67cee4bdf49225915f5945a872e3/guided_diffusion/gaussian_diffusion.py#L847-L849 + for the given timesteps using the provided noise scheduler. + + Args: + noise_scheduler (`NoiseScheduler`): + An object containing the noise schedule parameters, specifically `alphas_cumprod`, which is used to compute + the SNR values. + timesteps (`torch.Tensor`): + A tensor of timesteps for which the SNR is computed. + + Returns: + `torch.Tensor`: A tensor containing the computed SNR values for each timestep. + """ + alphas_cumprod = noise_scheduler.alphas_cumprod + sqrt_alphas_cumprod = alphas_cumprod**0.5 + sqrt_one_minus_alphas_cumprod = (1.0 - alphas_cumprod) ** 0.5 + + # Expand the tensors. + # Adapted from https://github.com/TiankaiHang/Min-SNR-Diffusion-Training/blob/521b624bd70c67cee4bdf49225915f5945a872e3/guided_diffusion/gaussian_diffusion.py#L1026 + sqrt_alphas_cumprod = sqrt_alphas_cumprod.to(device=timesteps.device)[timesteps].float() + while len(sqrt_alphas_cumprod.shape) < len(timesteps.shape): + sqrt_alphas_cumprod = sqrt_alphas_cumprod[..., None] + alpha = sqrt_alphas_cumprod.expand(timesteps.shape) + + sqrt_one_minus_alphas_cumprod = sqrt_one_minus_alphas_cumprod.to(device=timesteps.device)[timesteps].float() + while len(sqrt_one_minus_alphas_cumprod.shape) < len(timesteps.shape): + sqrt_one_minus_alphas_cumprod = sqrt_one_minus_alphas_cumprod[..., None] + sigma = sqrt_one_minus_alphas_cumprod.expand(timesteps.shape) + + # Compute SNR. + snr = (alpha / sigma) ** 2 + return snr + + +def resolve_interpolation_mode(interpolation_type: str): + """ + Maps a string describing an interpolation function to the corresponding torchvision `InterpolationMode` enum. The + full list of supported enums is documented at + https://pytorch.org/vision/0.9/transforms.html#torchvision.transforms.functional.InterpolationMode. + + Args: + interpolation_type (`str`): + A string describing an interpolation method. Currently, `bilinear`, `bicubic`, `box`, `nearest`, + `nearest_exact`, `hamming`, and `lanczos` are supported, corresponding to the supported interpolation modes + in torchvision. + + Returns: + `torchvision.transforms.InterpolationMode`: an `InterpolationMode` enum used by torchvision's `resize` + transform. + """ + if not is_torchvision_available(): + raise ImportError( + "Please make sure to install `torchvision` to be able to use the `resolve_interpolation_mode()` function." + ) + + if interpolation_type == "bilinear": + interpolation_mode = transforms.InterpolationMode.BILINEAR + elif interpolation_type == "bicubic": + interpolation_mode = transforms.InterpolationMode.BICUBIC + elif interpolation_type == "box": + interpolation_mode = transforms.InterpolationMode.BOX + elif interpolation_type == "nearest": + interpolation_mode = transforms.InterpolationMode.NEAREST + elif interpolation_type == "nearest_exact": + interpolation_mode = transforms.InterpolationMode.NEAREST_EXACT + elif interpolation_type == "hamming": + interpolation_mode = transforms.InterpolationMode.HAMMING + elif interpolation_type == "lanczos": + interpolation_mode = transforms.InterpolationMode.LANCZOS + else: + raise ValueError( + f"The given interpolation mode {interpolation_type} is not supported. Currently supported interpolation" + f" modes are `bilinear`, `bicubic`, `box`, `nearest`, `nearest_exact`, `hamming`, and `lanczos`." + ) + + return interpolation_mode + + +def compute_dream_and_update_latents( + unet: UNet2DConditionModel, + noise_scheduler: SchedulerMixin, + timesteps: torch.Tensor, + noise: torch.Tensor, + noisy_latents: torch.Tensor, + target: torch.Tensor, + encoder_hidden_states: torch.Tensor, + dream_detail_preservation: float = 1.0, +) -> Tuple[Optional[torch.Tensor], Optional[torch.Tensor]]: + """ + Implements "DREAM (Diffusion Rectification and Estimation-Adaptive Models)" from + https://huggingface.co/papers/2312.00210. DREAM helps align training with sampling to help training be more + efficient and accurate at the cost of an extra forward step without gradients. + + Args: + `unet`: The state unet to use to make a prediction. + `noise_scheduler`: The noise scheduler used to add noise for the given timestep. + `timesteps`: The timesteps for the noise_scheduler to user. + `noise`: A tensor of noise in the shape of noisy_latents. + `noisy_latents`: Previously noise latents from the training loop. + `target`: The ground-truth tensor to predict after eps is removed. + `encoder_hidden_states`: Text embeddings from the text model. + `dream_detail_preservation`: A float value that indicates detail preservation level. + See reference. + + Returns: + `tuple[torch.Tensor, torch.Tensor]`: Adjusted noisy_latents and target. + """ + alphas_cumprod = noise_scheduler.alphas_cumprod.to(timesteps.device)[timesteps, None, None, None] + sqrt_one_minus_alphas_cumprod = (1.0 - alphas_cumprod) ** 0.5 + + # The paper uses lambda = sqrt(1 - alpha) ** p, with p = 1 in their experiments. + dream_lambda = sqrt_one_minus_alphas_cumprod**dream_detail_preservation + + pred = None + with torch.no_grad(): + pred = unet(noisy_latents, timesteps, encoder_hidden_states).sample + + _noisy_latents, _target = (None, None) + if noise_scheduler.config.prediction_type == "epsilon": + predicted_noise = pred + delta_noise = (noise - predicted_noise).detach() + delta_noise.mul_(dream_lambda) + _noisy_latents = noisy_latents.add(sqrt_one_minus_alphas_cumprod * delta_noise) + _target = target.add(delta_noise) + elif noise_scheduler.config.prediction_type == "v_prediction": + raise NotImplementedError("DREAM has not been implemented for v-prediction") + else: + raise ValueError(f"Unknown prediction type {noise_scheduler.config.prediction_type}") + + return _noisy_latents, _target + + +def unet_lora_state_dict(unet: UNet2DConditionModel) -> Dict[str, torch.Tensor]: + r""" + Returns: + A state dict containing just the LoRA parameters. + """ + lora_state_dict = {} + + for name, module in unet.named_modules(): + if hasattr(module, "set_lora_layer"): + lora_layer = getattr(module, "lora_layer") + if lora_layer is not None: + current_lora_layer_sd = lora_layer.state_dict() + for lora_layer_matrix_name, lora_param in current_lora_layer_sd.items(): + # The matrix name can either be "down" or "up". + lora_state_dict[f"{name}.lora.{lora_layer_matrix_name}"] = lora_param + + return lora_state_dict + + +def cast_training_params(model: Union[torch.nn.Module, List[torch.nn.Module]], dtype=torch.float32): + """ + Casts the training parameters of the model to the specified data type. + + Args: + model: The PyTorch model whose parameters will be cast. + dtype: The data type to which the model parameters will be cast. + """ + if not isinstance(model, list): + model = [model] + for m in model: + for param in m.parameters(): + # only upcast trainable parameters into fp32 + if param.requires_grad: + param.data = param.to(dtype) + + +def _set_state_dict_into_text_encoder( + lora_state_dict: Dict[str, torch.Tensor], prefix: str, text_encoder: torch.nn.Module +): + """ + Sets the `lora_state_dict` into `text_encoder` coming from `transformers`. + + Args: + lora_state_dict: The state dictionary to be set. + prefix: String identifier to retrieve the portion of the state dict that belongs to `text_encoder`. + text_encoder: Where the `lora_state_dict` is to be set. + """ + + text_encoder_state_dict = { + f"{k.replace(prefix, '')}": v for k, v in lora_state_dict.items() if k.startswith(prefix) + } + text_encoder_state_dict = convert_state_dict_to_peft(convert_state_dict_to_diffusers(text_encoder_state_dict)) + set_peft_model_state_dict(text_encoder, text_encoder_state_dict, adapter_name="default") + + +def compute_density_for_timestep_sampling( + weighting_scheme: str, + batch_size: int, + logit_mean: float = None, + logit_std: float = None, + mode_scale: float = None, + device: Union[torch.device, str] = "cpu", + generator: Optional[torch.Generator] = None, +): + """ + Compute the density for sampling the timesteps when doing SD3 training. + + Courtesy: This was contributed by Rafie Walker in https://github.com/huggingface/diffusers/pull/8528. + + SD3 paper reference: https://huggingface.co/papers/2403.03206v1. + """ + if weighting_scheme == "logit_normal": + u = torch.normal(mean=logit_mean, std=logit_std, size=(batch_size,), device=device, generator=generator) + u = torch.nn.functional.sigmoid(u) + elif weighting_scheme == "mode": + u = torch.rand(size=(batch_size,), device=device, generator=generator) + u = 1 - u - mode_scale * (torch.cos(math.pi * u / 2) ** 2 - 1 + u) + else: + u = torch.rand(size=(batch_size,), device=device, generator=generator) + return u + + +def compute_loss_weighting_for_sd3(weighting_scheme: str, sigmas=None): + """ + Computes loss weighting scheme for SD3 training. + + Courtesy: This was contributed by Rafie Walker in https://github.com/huggingface/diffusers/pull/8528. + + SD3 paper reference: https://huggingface.co/papers/2403.03206v1. + """ + if weighting_scheme == "sigma_sqrt": + weighting = (sigmas**-2.0).float() + elif weighting_scheme == "cosmap": + bot = 1 - 2 * sigmas + 2 * sigmas**2 + weighting = 2 / (math.pi * bot) + else: + weighting = torch.ones_like(sigmas) + return weighting + + +def free_memory(): + """ + Runs garbage collection. Then clears the cache of the available accelerator. + """ + gc.collect() + + if torch.cuda.is_available(): + torch.cuda.empty_cache() + elif torch.backends.mps.is_available(): + torch.mps.empty_cache() + elif is_torch_npu_available(): + torch_npu.npu.empty_cache() + elif hasattr(torch, "xpu") and torch.xpu.is_available(): + torch.xpu.empty_cache() + + +# Adapted from torch-ema https://github.com/fadel/pytorch_ema/blob/master/torch_ema/ema.py#L14 +class EMAModel: + """ + Exponential Moving Average of models weights + """ + + def __init__( + self, + parameters: Iterable[torch.nn.Parameter], + decay: float = 0.9999, + min_decay: float = 0.0, + update_after_step: int = 0, + use_ema_warmup: bool = False, + inv_gamma: Union[float, int] = 1.0, + power: Union[float, int] = 2 / 3, + foreach: bool = False, + model_cls: Optional[Any] = None, + model_config: Dict[str, Any] = None, + **kwargs, + ): + """ + Args: + parameters (Iterable[torch.nn.Parameter]): The parameters to track. + decay (float): The decay factor for the exponential moving average. + min_decay (float): The minimum decay factor for the exponential moving average. + update_after_step (int): The number of steps to wait before starting to update the EMA weights. + use_ema_warmup (bool): Whether to use EMA warmup. + inv_gamma (float): + Inverse multiplicative factor of EMA warmup. Default: 1. Only used if `use_ema_warmup` is True. + power (float): Exponential factor of EMA warmup. Default: 2/3. Only used if `use_ema_warmup` is True. + foreach (bool): Use torch._foreach functions for updating shadow parameters. Should be faster. + device (Optional[Union[str, torch.device]]): The device to store the EMA weights on. If None, the EMA + weights will be stored on CPU. + + @crowsonkb's notes on EMA Warmup: + If gamma=1 and power=1, implements a simple average. gamma=1, power=2/3 are good values for models you plan + to train for a million or more steps (reaches decay factor 0.999 at 31.6K steps, 0.9999 at 1M steps), + gamma=1, power=3/4 for models you plan to train for less (reaches decay factor 0.999 at 10K steps, 0.9999 + at 215.4k steps). + """ + + if isinstance(parameters, torch.nn.Module): + deprecation_message = ( + "Passing a `torch.nn.Module` to `ExponentialMovingAverage` is deprecated. " + "Please pass the parameters of the module instead." + ) + deprecate( + "passing a `torch.nn.Module` to `ExponentialMovingAverage`", + "1.0.0", + deprecation_message, + standard_warn=False, + ) + parameters = parameters.parameters() + + # set use_ema_warmup to True if a torch.nn.Module is passed for backwards compatibility + use_ema_warmup = True + + if kwargs.get("max_value", None) is not None: + deprecation_message = "The `max_value` argument is deprecated. Please use `decay` instead." + deprecate("max_value", "1.0.0", deprecation_message, standard_warn=False) + decay = kwargs["max_value"] + + if kwargs.get("min_value", None) is not None: + deprecation_message = "The `min_value` argument is deprecated. Please use `min_decay` instead." + deprecate("min_value", "1.0.0", deprecation_message, standard_warn=False) + min_decay = kwargs["min_value"] + + parameters = list(parameters) + self.shadow_params = [p.clone().detach() for p in parameters] + + if kwargs.get("device", None) is not None: + deprecation_message = "The `device` argument is deprecated. Please use `to` instead." + deprecate("device", "1.0.0", deprecation_message, standard_warn=False) + self.to(device=kwargs["device"]) + + self.temp_stored_params = None + + self.decay = decay + self.min_decay = min_decay + self.update_after_step = update_after_step + self.use_ema_warmup = use_ema_warmup + self.inv_gamma = inv_gamma + self.power = power + self.optimization_step = 0 + self.cur_decay_value = None # set in `step()` + self.foreach = foreach + + self.model_cls = model_cls + self.model_config = model_config + + @classmethod + def from_pretrained(cls, path, model_cls, foreach=False) -> "EMAModel": + _, ema_kwargs = model_cls.from_config(path, return_unused_kwargs=True) + model = model_cls.from_pretrained(path) + + ema_model = cls(model.parameters(), model_cls=model_cls, model_config=model.config, foreach=foreach) + + ema_model.load_state_dict(ema_kwargs) + return ema_model + + def save_pretrained(self, path): + if self.model_cls is None: + raise ValueError("`save_pretrained` can only be used if `model_cls` was defined at __init__.") + + if self.model_config is None: + raise ValueError("`save_pretrained` can only be used if `model_config` was defined at __init__.") + + model = self.model_cls.from_config(self.model_config) + state_dict = self.state_dict() + state_dict.pop("shadow_params", None) + + model.register_to_config(**state_dict) + self.copy_to(model.parameters()) + model.save_pretrained(path) + + def get_decay(self, optimization_step: int) -> float: + """ + Compute the decay factor for the exponential moving average. + """ + step = max(0, optimization_step - self.update_after_step - 1) + + if step <= 0: + return 0.0 + + if self.use_ema_warmup: + cur_decay_value = 1 - (1 + step / self.inv_gamma) ** -self.power + else: + cur_decay_value = (1 + step) / (10 + step) + + cur_decay_value = min(cur_decay_value, self.decay) + # make sure decay is not smaller than min_decay + cur_decay_value = max(cur_decay_value, self.min_decay) + return cur_decay_value + + @torch.no_grad() + def step(self, parameters: Iterable[torch.nn.Parameter]): + if isinstance(parameters, torch.nn.Module): + deprecation_message = ( + "Passing a `torch.nn.Module` to `ExponentialMovingAverage.step` is deprecated. " + "Please pass the parameters of the module instead." + ) + deprecate( + "passing a `torch.nn.Module` to `ExponentialMovingAverage.step`", + "1.0.0", + deprecation_message, + standard_warn=False, + ) + parameters = parameters.parameters() + + parameters = list(parameters) + + self.optimization_step += 1 + + # Compute the decay factor for the exponential moving average. + decay = self.get_decay(self.optimization_step) + self.cur_decay_value = decay + one_minus_decay = 1 - decay + + context_manager = contextlib.nullcontext() + + if self.foreach: + if is_transformers_available() and transformers.integrations.deepspeed.is_deepspeed_zero3_enabled(): + context_manager = deepspeed.zero.GatheredParameters(parameters, modifier_rank=None) + + with context_manager: + params_grad = [param for param in parameters if param.requires_grad] + s_params_grad = [ + s_param for s_param, param in zip(self.shadow_params, parameters) if param.requires_grad + ] + + if len(params_grad) < len(parameters): + torch._foreach_copy_( + [s_param for s_param, param in zip(self.shadow_params, parameters) if not param.requires_grad], + [param for param in parameters if not param.requires_grad], + non_blocking=True, + ) + + torch._foreach_sub_( + s_params_grad, torch._foreach_sub(s_params_grad, params_grad), alpha=one_minus_decay + ) + + else: + for s_param, param in zip(self.shadow_params, parameters): + if is_transformers_available() and transformers.integrations.deepspeed.is_deepspeed_zero3_enabled(): + context_manager = deepspeed.zero.GatheredParameters(param, modifier_rank=None) + + with context_manager: + if param.requires_grad: + s_param.sub_(one_minus_decay * (s_param - param)) + else: + s_param.copy_(param) + + def copy_to(self, parameters: Iterable[torch.nn.Parameter]) -> None: + """ + Copy current averaged parameters into given collection of parameters. + + Args: + parameters: Iterable of `torch.nn.Parameter`; the parameters to be + updated with the stored moving averages. If `None`, the parameters with which this + `ExponentialMovingAverage` was initialized will be used. + """ + parameters = list(parameters) + if self.foreach: + torch._foreach_copy_( + [param.data for param in parameters], + [s_param.to(param.device).data for s_param, param in zip(self.shadow_params, parameters)], + ) + else: + for s_param, param in zip(self.shadow_params, parameters): + param.data.copy_(s_param.to(param.device).data) + + def pin_memory(self) -> None: + r""" + Move internal buffers of the ExponentialMovingAverage to pinned memory. Useful for non-blocking transfers for + offloading EMA params to the host. + """ + + self.shadow_params = [p.pin_memory() for p in self.shadow_params] + + def to(self, device=None, dtype=None, non_blocking=False) -> None: + r""" + Move internal buffers of the ExponentialMovingAverage to `device`. + + Args: + device: like `device` argument to `torch.Tensor.to` + """ + # .to() on the tensors handles None correctly + self.shadow_params = [ + p.to(device=device, dtype=dtype, non_blocking=non_blocking) + if p.is_floating_point() + else p.to(device=device, non_blocking=non_blocking) + for p in self.shadow_params + ] + + def state_dict(self) -> dict: + r""" + Returns the state of the ExponentialMovingAverage as a dict. This method is used by accelerate during + checkpointing to save the ema state dict. + """ + # Following PyTorch conventions, references to tensors are returned: + # "returns a reference to the state and not its copy!" - + # https://pytorch.org/tutorials/beginner/saving_loading_models.html#what-is-a-state-dict + return { + "decay": self.decay, + "min_decay": self.min_decay, + "optimization_step": self.optimization_step, + "update_after_step": self.update_after_step, + "use_ema_warmup": self.use_ema_warmup, + "inv_gamma": self.inv_gamma, + "power": self.power, + "shadow_params": self.shadow_params, + } + + def store(self, parameters: Iterable[torch.nn.Parameter]) -> None: + r""" + Saves the current parameters for restoring later. + + Args: + parameters: Iterable of `torch.nn.Parameter`. The parameters to be temporarily stored. + """ + self.temp_stored_params = [param.detach().cpu().clone() for param in parameters] + + def restore(self, parameters: Iterable[torch.nn.Parameter]) -> None: + r""" + Restore the parameters stored with the `store` method. Useful to validate the model with EMA parameters + without: affecting the original optimization process. Store the parameters before the `copy_to()` method. After + validation (or model saving), use this to restore the former parameters. + + Args: + parameters: Iterable of `torch.nn.Parameter`; the parameters to be + updated with the stored parameters. If `None`, the parameters with which this + `ExponentialMovingAverage` was initialized will be used. + """ + + if self.temp_stored_params is None: + raise RuntimeError("This ExponentialMovingAverage has no `store()`ed weights to `restore()`") + if self.foreach: + torch._foreach_copy_( + [param.data for param in parameters], [c_param.data for c_param in self.temp_stored_params] + ) + else: + for c_param, param in zip(self.temp_stored_params, parameters): + param.data.copy_(c_param.data) + + # Better memory-wise. + self.temp_stored_params = None + + def load_state_dict(self, state_dict: dict) -> None: + r""" + Loads the ExponentialMovingAverage state. This method is used by accelerate during checkpointing to save the + ema state dict. + + Args: + state_dict (dict): EMA state. Should be an object returned + from a call to :meth:`state_dict`. + """ + # deepcopy, to be consistent with module API + state_dict = copy.deepcopy(state_dict) + + self.decay = state_dict.get("decay", self.decay) + if self.decay < 0.0 or self.decay > 1.0: + raise ValueError("Decay must be between 0 and 1") + + self.min_decay = state_dict.get("min_decay", self.min_decay) + if not isinstance(self.min_decay, float): + raise ValueError("Invalid min_decay") + + self.optimization_step = state_dict.get("optimization_step", self.optimization_step) + if not isinstance(self.optimization_step, int): + raise ValueError("Invalid optimization_step") + + self.update_after_step = state_dict.get("update_after_step", self.update_after_step) + if not isinstance(self.update_after_step, int): + raise ValueError("Invalid update_after_step") + + self.use_ema_warmup = state_dict.get("use_ema_warmup", self.use_ema_warmup) + if not isinstance(self.use_ema_warmup, bool): + raise ValueError("Invalid use_ema_warmup") + + self.inv_gamma = state_dict.get("inv_gamma", self.inv_gamma) + if not isinstance(self.inv_gamma, (float, int)): + raise ValueError("Invalid inv_gamma") + + self.power = state_dict.get("power", self.power) + if not isinstance(self.power, (float, int)): + raise ValueError("Invalid power") + + shadow_params = state_dict.get("shadow_params", None) + if shadow_params is not None: + self.shadow_params = shadow_params + if not isinstance(self.shadow_params, list): + raise ValueError("shadow_params must be a list") + if not all(isinstance(p, torch.Tensor) for p in self.shadow_params): + raise ValueError("shadow_params must all be Tensors") diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/__init__.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..2df05cb8eb36fecaa22d12435008dd9903fecc3f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/__init__.py @@ -0,0 +1,153 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +import os + +from packaging import version + +from .. import __version__ +from .constants import ( + CONFIG_NAME, + DEPRECATED_REVISION_ARGS, + DIFFUSERS_DYNAMIC_MODULE_NAME, + FLAX_WEIGHTS_NAME, + GGUF_FILE_EXTENSION, + HF_MODULES_CACHE, + HUGGINGFACE_CO_RESOLVE_ENDPOINT, + MIN_PEFT_VERSION, + ONNX_EXTERNAL_WEIGHTS_NAME, + ONNX_WEIGHTS_NAME, + SAFE_WEIGHTS_INDEX_NAME, + SAFETENSORS_FILE_EXTENSION, + SAFETENSORS_WEIGHTS_NAME, + USE_PEFT_BACKEND, + WEIGHTS_INDEX_NAME, + WEIGHTS_NAME, +) +from .deprecation_utils import deprecate +from .doc_utils import replace_example_docstring +from .dynamic_modules_utils import get_class_from_dynamic_module +from .export_utils import export_to_gif, export_to_obj, export_to_ply, export_to_video +from .hub_utils import ( + PushToHubMixin, + _add_variant, + _get_checkpoint_shard_files, + _get_model_file, + extract_commit_hash, + http_user_agent, +) +from .import_utils import ( + BACKENDS_MAPPING, + DIFFUSERS_SLOW_IMPORT, + ENV_VARS_TRUE_AND_AUTO_VALUES, + ENV_VARS_TRUE_VALUES, + USE_JAX, + USE_TF, + USE_TORCH, + DummyObject, + OptionalDependencyNotAvailable, + _LazyModule, + get_objects_from_module, + is_accelerate_available, + is_accelerate_version, + is_better_profanity_available, + is_bitsandbytes_available, + is_bitsandbytes_version, + is_bs4_available, + is_cosmos_guardrail_available, + is_flax_available, + is_ftfy_available, + is_gguf_available, + is_gguf_version, + is_google_colab, + is_hf_hub_version, + is_hpu_available, + is_inflect_available, + is_invisible_watermark_available, + is_k_diffusion_available, + is_k_diffusion_version, + is_librosa_available, + is_matplotlib_available, + is_nltk_available, + is_note_seq_available, + is_onnx_available, + is_opencv_available, + is_optimum_quanto_available, + is_optimum_quanto_version, + is_peft_available, + is_peft_version, + is_pytorch_retinaface_available, + is_safetensors_available, + is_scipy_available, + is_sentencepiece_available, + is_tensorboard_available, + is_timm_available, + is_torch_available, + is_torch_npu_available, + is_torch_version, + is_torch_xla_available, + is_torch_xla_version, + is_torchao_available, + is_torchao_version, + is_torchsde_available, + is_torchvision_available, + is_transformers_available, + is_transformers_version, + is_unidecode_available, + is_wandb_available, + is_xformers_available, + requires_backends, +) +from .loading_utils import get_module_from_name, get_submodule_by_name, load_image, load_video +from .logging import get_logger +from .outputs import BaseOutput +from .peft_utils import ( + check_peft_version, + delete_adapter_layers, + get_adapter_name, + get_peft_kwargs, + recurse_remove_peft_layers, + scale_lora_layers, + set_adapter_layers, + set_weights_and_activate_adapters, + unscale_lora_layers, +) +from .pil_utils import PIL_INTERPOLATION, make_image_grid, numpy_to_pil, pt_to_pil +from .remote_utils import remote_decode +from .state_dict_utils import ( + convert_all_state_dict_to_peft, + convert_state_dict_to_diffusers, + convert_state_dict_to_kohya, + convert_state_dict_to_peft, + convert_unet_state_dict_to_peft, + state_dict_all_zero, +) +from .typing_utils import _get_detailed_type, _is_valid_type + + +logger = get_logger(__name__) + + +def check_min_version(min_version): + if version.parse(__version__) < version.parse(min_version): + if "dev" in min_version: + error_message = ( + "This example requires a source install from HuggingFace diffusers (see " + "`https://huggingface.co/docs/diffusers/installation#install-from-source`)," + ) + else: + error_message = f"This example requires a minimum version of {min_version}," + error_message += f" but the version found is {__version__}.\n" + raise ImportError(error_message) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/accelerate_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/accelerate_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..99a8b3a47c256cc80dbd5de7d14101dcc7a9ff9a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/accelerate_utils.py @@ -0,0 +1,48 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Accelerate utilities: Utilities related to accelerate +""" + +from packaging import version + +from .import_utils import is_accelerate_available + + +if is_accelerate_available(): + import accelerate + + +def apply_forward_hook(method): + """ + Decorator that applies a registered CpuOffload hook to an arbitrary function rather than `forward`. This is useful + for cases where a PyTorch module provides functions other than `forward` that should trigger a move to the + appropriate acceleration device. This is the case for `encode` and `decode` in [`AutoencoderKL`]. + + This decorator looks inside the internal `_hf_hook` property to find a registered offload hook. + + :param method: The method to decorate. This method should be a method of a PyTorch module. + """ + if not is_accelerate_available(): + return method + accelerate_version = version.parse(accelerate.__version__).base_version + if version.parse(accelerate_version) < version.parse("0.17.0"): + return method + + def wrapper(self, *args, **kwargs): + if hasattr(self, "_hf_hook") and hasattr(self._hf_hook, "pre_forward"): + self._hf_hook.pre_forward(self) + return method(self, *args, **kwargs) + + return wrapper diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/constants.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/constants.py new file mode 100644 index 0000000000000000000000000000000000000000..7c04287d33ed9e4b2030d8c76aed5ff06cbbb285 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/constants.py @@ -0,0 +1,70 @@ +# Copyright 2025 The HuggingFace Inc. team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import importlib +import os + +from huggingface_hub.constants import HF_HOME +from packaging import version + +from ..dependency_versions_check import dep_version_check +from .import_utils import ENV_VARS_TRUE_VALUES, is_peft_available, is_transformers_available + + +MIN_PEFT_VERSION = "0.6.0" +MIN_TRANSFORMERS_VERSION = "4.34.0" +_CHECK_PEFT = os.environ.get("_CHECK_PEFT", "1") in ENV_VARS_TRUE_VALUES + + +CONFIG_NAME = "config.json" +WEIGHTS_NAME = "diffusion_pytorch_model.bin" +WEIGHTS_INDEX_NAME = "diffusion_pytorch_model.bin.index.json" +FLAX_WEIGHTS_NAME = "diffusion_flax_model.msgpack" +ONNX_WEIGHTS_NAME = "model.onnx" +SAFETENSORS_WEIGHTS_NAME = "diffusion_pytorch_model.safetensors" +SAFE_WEIGHTS_INDEX_NAME = "diffusion_pytorch_model.safetensors.index.json" +SAFETENSORS_FILE_EXTENSION = "safetensors" +GGUF_FILE_EXTENSION = "gguf" +ONNX_EXTERNAL_WEIGHTS_NAME = "weights.pb" +HUGGINGFACE_CO_RESOLVE_ENDPOINT = os.environ.get("HF_ENDPOINT", "https://huggingface.co") +DIFFUSERS_DYNAMIC_MODULE_NAME = "diffusers_modules" +HF_MODULES_CACHE = os.getenv("HF_MODULES_CACHE", os.path.join(HF_HOME, "modules")) +DEPRECATED_REVISION_ARGS = ["fp16", "non-ema"] +DIFFUSERS_REQUEST_TIMEOUT = 60 + +# Below should be `True` if the current version of `peft` and `transformers` are compatible with +# PEFT backend. Will automatically fall back to PEFT backend if the correct versions of the libraries are +# available. +# For PEFT it is has to be greater than or equal to 0.6.0 and for transformers it has to be greater than or equal to 4.34.0. +_required_peft_version = is_peft_available() and version.parse( + version.parse(importlib.metadata.version("peft")).base_version +) >= version.parse(MIN_PEFT_VERSION) +_required_transformers_version = is_transformers_available() and version.parse( + version.parse(importlib.metadata.version("transformers")).base_version +) >= version.parse(MIN_TRANSFORMERS_VERSION) + +USE_PEFT_BACKEND = _required_peft_version and _required_transformers_version + +if USE_PEFT_BACKEND and _CHECK_PEFT: + dep_version_check("peft") + + +DECODE_ENDPOINT_SD_V1 = "https://q1bj3bpq6kzilnsu.us-east-1.aws.endpoints.huggingface.cloud/" +DECODE_ENDPOINT_SD_XL = "https://x2dmsqunjd6k9prw.us-east-1.aws.endpoints.huggingface.cloud/" +DECODE_ENDPOINT_FLUX = "https://whhx50ex1aryqvw6.us-east-1.aws.endpoints.huggingface.cloud/" +DECODE_ENDPOINT_HUNYUAN_VIDEO = "https://o7ywnmrahorts457.us-east-1.aws.endpoints.huggingface.cloud/" + + +ENCODE_ENDPOINT_SD_V1 = "https://qc6479g0aac6qwy9.us-east-1.aws.endpoints.huggingface.cloud/" +ENCODE_ENDPOINT_SD_XL = "https://xjqqhmyn62rog84g.us-east-1.aws.endpoints.huggingface.cloud/" +ENCODE_ENDPOINT_FLUX = "https://ptccx55jz97f9zgo.us-east-1.aws.endpoints.huggingface.cloud/" diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/deprecation_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/deprecation_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..4f001b3047d60c7572d770ad93595af3e62ae45e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/deprecation_utils.py @@ -0,0 +1,49 @@ +import inspect +import warnings +from typing import Any, Dict, Optional, Union + +from packaging import version + + +def deprecate(*args, take_from: Optional[Union[Dict, Any]] = None, standard_warn=True, stacklevel=2): + from .. import __version__ + + deprecated_kwargs = take_from + values = () + if not isinstance(args[0], tuple): + args = (args,) + + for attribute, version_name, message in args: + if version.parse(version.parse(__version__).base_version) >= version.parse(version_name): + raise ValueError( + f"The deprecation tuple {(attribute, version_name, message)} should be removed since diffusers'" + f" version {__version__} is >= {version_name}" + ) + + warning = None + if isinstance(deprecated_kwargs, dict) and attribute in deprecated_kwargs: + values += (deprecated_kwargs.pop(attribute),) + warning = f"The `{attribute}` argument is deprecated and will be removed in version {version_name}." + elif hasattr(deprecated_kwargs, attribute): + values += (getattr(deprecated_kwargs, attribute),) + warning = f"The `{attribute}` attribute is deprecated and will be removed in version {version_name}." + elif deprecated_kwargs is None: + warning = f"`{attribute}` is deprecated and will be removed in version {version_name}." + + if warning is not None: + warning = warning + " " if standard_warn else "" + warnings.warn(warning + message, FutureWarning, stacklevel=stacklevel) + + if isinstance(deprecated_kwargs, dict) and len(deprecated_kwargs) > 0: + call_frame = inspect.getouterframes(inspect.currentframe())[1] + filename = call_frame.filename + line_number = call_frame.lineno + function = call_frame.function + key, value = next(iter(deprecated_kwargs.items())) + raise TypeError(f"{function} in {filename} line {line_number - 1} got an unexpected keyword argument `{key}`") + + if len(values) == 0: + return + elif len(values) == 1: + return values[0] + return values diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/doc_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/doc_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..fe633e6836422f22618548b3f6d946d6b073650f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/doc_utils.py @@ -0,0 +1,39 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Doc utilities: Utilities related to documentation +""" + +import re + + +def replace_example_docstring(example_docstring): + def docstring_decorator(fn): + func_doc = fn.__doc__ + lines = func_doc.split("\n") + i = 0 + while i < len(lines) and re.search(r"^\s*Examples?:\s*$", lines[i]) is None: + i += 1 + if i < len(lines): + lines[i] = example_docstring + func_doc = "\n".join(lines) + else: + raise ValueError( + f"The function {fn} should have an empty 'Examples:' in its docstring as placeholder, " + f"current docstring is:\n{func_doc}" + ) + fn.__doc__ = func_doc + return fn + + return docstring_decorator diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_bitsandbytes_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_bitsandbytes_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..2dc589428de960f9c46f5a22874e2ef6475c418c --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_bitsandbytes_objects.py @@ -0,0 +1,17 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class BitsAndBytesConfig(metaclass=DummyObject): + _backends = ["bitsandbytes"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["bitsandbytes"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["bitsandbytes"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["bitsandbytes"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_flax_and_transformers_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_flax_and_transformers_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..5e65e5349bb0a6a0bac62cddf0ce0fad64237c68 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_flax_and_transformers_objects.py @@ -0,0 +1,77 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class FlaxStableDiffusionControlNetPipeline(metaclass=DummyObject): + _backends = ["flax", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax", "transformers"]) + + +class FlaxStableDiffusionImg2ImgPipeline(metaclass=DummyObject): + _backends = ["flax", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax", "transformers"]) + + +class FlaxStableDiffusionInpaintPipeline(metaclass=DummyObject): + _backends = ["flax", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax", "transformers"]) + + +class FlaxStableDiffusionPipeline(metaclass=DummyObject): + _backends = ["flax", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax", "transformers"]) + + +class FlaxStableDiffusionXLPipeline(metaclass=DummyObject): + _backends = ["flax", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax", "transformers"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_flax_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_flax_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..5fa8dbc819316e96f7483addba43f90b9d8f397b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_flax_objects.py @@ -0,0 +1,212 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class FlaxControlNetModel(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + +class FlaxModelMixin(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + +class FlaxUNet2DConditionModel(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + +class FlaxAutoencoderKL(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + +class FlaxDiffusionPipeline(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + +class FlaxDDIMScheduler(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + +class FlaxDDPMScheduler(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + +class FlaxDPMSolverMultistepScheduler(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + +class FlaxEulerDiscreteScheduler(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + +class FlaxKarrasVeScheduler(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + +class FlaxLMSDiscreteScheduler(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + +class FlaxPNDMScheduler(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + +class FlaxSchedulerMixin(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + +class FlaxScoreSdeVeScheduler(metaclass=DummyObject): + _backends = ["flax"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["flax"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["flax"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_gguf_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_gguf_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..4a6d9a060a1397c5ef0e402e67170960bb3de516 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_gguf_objects.py @@ -0,0 +1,17 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class GGUFQuantizationConfig(metaclass=DummyObject): + _backends = ["gguf"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["gguf"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["gguf"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["gguf"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_note_seq_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_note_seq_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..c02d0b015aedc37c01fb3b843bc79547aae5da68 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_note_seq_objects.py @@ -0,0 +1,17 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class MidiProcessor(metaclass=DummyObject): + _backends = ["note_seq"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["note_seq"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["note_seq"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["note_seq"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_onnx_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_onnx_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..bde5f6ad0793e2d81bc638600b46ff81748d09ee --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_onnx_objects.py @@ -0,0 +1,17 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class OnnxRuntimeModel(metaclass=DummyObject): + _backends = ["onnx"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["onnx"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["onnx"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["onnx"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_optimum_quanto_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_optimum_quanto_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..44f8eaffc2460360d17720578b8224496f91cf94 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_optimum_quanto_objects.py @@ -0,0 +1,17 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class QuantoConfig(metaclass=DummyObject): + _backends = ["optimum_quanto"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["optimum_quanto"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["optimum_quanto"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["optimum_quanto"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_pt_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_pt_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..97bc3f317b323852e3ab1daa7af4de6aa8d79e15 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_pt_objects.py @@ -0,0 +1,2078 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class FasterCacheConfig(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class HookRegistry(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class PyramidAttentionBroadcastConfig(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +def apply_faster_cache(*args, **kwargs): + requires_backends(apply_faster_cache, ["torch"]) + + +def apply_pyramid_attention_broadcast(*args, **kwargs): + requires_backends(apply_pyramid_attention_broadcast, ["torch"]) + + +class AllegroTransformer3DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AsymmetricAutoencoderKL(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AuraFlowTransformer2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoencoderDC(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoencoderKL(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoencoderKLAllegro(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoencoderKLCogVideoX(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoencoderKLCosmos(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoencoderKLHunyuanVideo(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoencoderKLLTXVideo(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoencoderKLMagvit(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoencoderKLMochi(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoencoderKLTemporalDecoder(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoencoderKLWan(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoencoderOobleck(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoencoderTiny(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class CacheMixin(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class CogVideoXTransformer3DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class CogView3PlusTransformer2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class CogView4Transformer2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class ConsisIDTransformer3DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class ConsistencyDecoderVAE(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class ControlNetModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class ControlNetUnionModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class ControlNetXSAdapter(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class CosmosTransformer3DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DiTTransformer2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class EasyAnimateTransformer3DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class FluxControlNetModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class FluxMultiControlNetModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class FluxTransformer2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class HiDreamImageTransformer2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class HunyuanDiT2DControlNetModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class HunyuanDiT2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class HunyuanDiT2DMultiControlNetModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class HunyuanVideoFramepackTransformer3DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class HunyuanVideoTransformer3DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class I2VGenXLUNet(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class Kandinsky3UNet(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class LatteTransformer3DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class LTXVideoTransformer3DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class Lumina2Transformer2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class LuminaNextDiT2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class MochiTransformer3DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class ModelMixin(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class MotionAdapter(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class MultiAdapter(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class MultiControlNetModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class OmniGenTransformer2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class PixArtTransformer2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class PriorTransformer(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class SanaControlNetModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class SanaTransformer2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class SD3ControlNetModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class SD3MultiControlNetModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class SD3Transformer2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class SparseControlNetModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class StableAudioDiTModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class T2IAdapter(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class T5FilmDecoder(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class Transformer2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class TransformerTemporalModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class UNet1DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class UNet2DConditionModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class UNet2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class UNet3DConditionModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class UNetControlNetXSModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class UNetMotionModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class UNetSpatioTemporalConditionModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class UVit2DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class VQModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class WanTransformer3DModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +def get_constant_schedule(*args, **kwargs): + requires_backends(get_constant_schedule, ["torch"]) + + +def get_constant_schedule_with_warmup(*args, **kwargs): + requires_backends(get_constant_schedule_with_warmup, ["torch"]) + + +def get_cosine_schedule_with_warmup(*args, **kwargs): + requires_backends(get_cosine_schedule_with_warmup, ["torch"]) + + +def get_cosine_with_hard_restarts_schedule_with_warmup(*args, **kwargs): + requires_backends(get_cosine_with_hard_restarts_schedule_with_warmup, ["torch"]) + + +def get_linear_schedule_with_warmup(*args, **kwargs): + requires_backends(get_linear_schedule_with_warmup, ["torch"]) + + +def get_polynomial_decay_schedule_with_warmup(*args, **kwargs): + requires_backends(get_polynomial_decay_schedule_with_warmup, ["torch"]) + + +def get_scheduler(*args, **kwargs): + requires_backends(get_scheduler, ["torch"]) + + +class AudioPipelineOutput(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoPipelineForImage2Image(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoPipelineForInpainting(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AutoPipelineForText2Image(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class BlipDiffusionControlNetPipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class BlipDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class CLIPImageProjection(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class ConsistencyModelPipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DanceDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DDIMPipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DDPMPipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DiffusionPipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DiTPipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class ImagePipelineOutput(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class KarrasVePipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class LDMPipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class LDMSuperResolutionPipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class PNDMPipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class RePaintPipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class ScoreSdeVePipeline(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class StableDiffusionMixin(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DiffusersQuantizer(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class AmusedScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class CMStochasticIterativeScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class CogVideoXDDIMScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class CogVideoXDPMScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DDIMInverseScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DDIMParallelScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DDIMScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DDPMParallelScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DDPMScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DDPMWuerstchenScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DEISMultistepScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DPMSolverMultistepInverseScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DPMSolverMultistepScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class DPMSolverSinglestepScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class EDMDPMSolverMultistepScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class EDMEulerScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class EulerAncestralDiscreteScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class EulerDiscreteScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class FlowMatchEulerDiscreteScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class FlowMatchHeunDiscreteScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class FlowMatchLCMScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class HeunDiscreteScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class IPNDMScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class KarrasVeScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class KDPM2AncestralDiscreteScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class KDPM2DiscreteScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class LCMScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class PNDMScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class RePaintScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class SASolverScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class SchedulerMixin(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class SCMScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class ScoreSdeVeScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class TCDScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class UnCLIPScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class UniPCMultistepScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class VQDiffusionScheduler(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + +class EMAModel(metaclass=DummyObject): + _backends = ["torch"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_librosa_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_librosa_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..2088bc4a744198284f22fe54e6f1055cf3568566 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_librosa_objects.py @@ -0,0 +1,32 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class AudioDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "librosa"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "librosa"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "librosa"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "librosa"]) + + +class Mel(metaclass=DummyObject): + _backends = ["torch", "librosa"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "librosa"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "librosa"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "librosa"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_scipy_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_scipy_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..a1ff25863822b04971d2c6dfdc17f5b28774cf05 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_scipy_objects.py @@ -0,0 +1,17 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class LMSDiscreteScheduler(metaclass=DummyObject): + _backends = ["torch", "scipy"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "scipy"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "scipy"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "scipy"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_torchsde_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_torchsde_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..6ff14231b9cc8c88effc4d11f7b439fa16bb7f20 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_torchsde_objects.py @@ -0,0 +1,32 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class CosineDPMSolverMultistepScheduler(metaclass=DummyObject): + _backends = ["torch", "torchsde"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "torchsde"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "torchsde"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "torchsde"]) + + +class DPMSolverSDEScheduler(metaclass=DummyObject): + _backends = ["torch", "torchsde"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "torchsde"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "torchsde"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "torchsde"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_and_k_diffusion_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_and_k_diffusion_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..2ab00c54ce2d7ca78f674085f0fe294d1f05c1e0 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_and_k_diffusion_objects.py @@ -0,0 +1,32 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class StableDiffusionKDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers", "k_diffusion"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers", "k_diffusion"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "k_diffusion"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "k_diffusion"]) + + +class StableDiffusionXLKDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers", "k_diffusion"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers", "k_diffusion"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "k_diffusion"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "k_diffusion"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_and_onnx_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_and_onnx_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..b7afad8226b87292100270e3e7daad6885be0e7f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_and_onnx_objects.py @@ -0,0 +1,92 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class OnnxStableDiffusionImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers", "onnx"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers", "onnx"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "onnx"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "onnx"]) + + +class OnnxStableDiffusionInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers", "onnx"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers", "onnx"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "onnx"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "onnx"]) + + +class OnnxStableDiffusionInpaintPipelineLegacy(metaclass=DummyObject): + _backends = ["torch", "transformers", "onnx"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers", "onnx"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "onnx"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "onnx"]) + + +class OnnxStableDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers", "onnx"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers", "onnx"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "onnx"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "onnx"]) + + +class OnnxStableDiffusionUpscalePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers", "onnx"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers", "onnx"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "onnx"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "onnx"]) + + +class StableDiffusionOnnxPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers", "onnx"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers", "onnx"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "onnx"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "onnx"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_and_opencv_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_and_opencv_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..c0c4d9df5eeeca4cca0a5147058eba70f89bcbc2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_and_opencv_objects.py @@ -0,0 +1,17 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class ConsisIDPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers", "opencv"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers", "opencv"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "opencv"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "opencv"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_and_sentencepiece_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_and_sentencepiece_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..349db10d1fa5b8505173e1578d3c83ea17e95fbc --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_and_sentencepiece_objects.py @@ -0,0 +1,47 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class KolorsImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers", "sentencepiece"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers", "sentencepiece"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "sentencepiece"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "sentencepiece"]) + + +class KolorsPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers", "sentencepiece"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers", "sentencepiece"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "sentencepiece"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "sentencepiece"]) + + +class KolorsPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers", "sentencepiece"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers", "sentencepiece"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "sentencepiece"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers", "sentencepiece"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..4ab6091c6dfc4df51633fa6a77ed3c5d991a71dc --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torch_and_transformers_objects.py @@ -0,0 +1,2942 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class AllegroPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AltDiffusionImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AltDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AmusedImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AmusedInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AmusedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffSDXLPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffSparseControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffVideoToVideoControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffVideoToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AudioLDM2Pipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AudioLDM2ProjectionModel(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AudioLDM2UNet2DConditionModel(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AudioLDMPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AuraFlowPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CLIPImageProjection(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogVideoXFunControlPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogVideoXImageToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogVideoXPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogVideoXVideoToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogView3PlusPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogView4ControlPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogView4Pipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class ConsisIDPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CosmosTextToWorldPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CosmosVideoToWorldPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CycleDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class EasyAnimateControlPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class EasyAnimateInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class EasyAnimatePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxControlImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxControlInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxControlNetImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxControlNetInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxControlPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxFillPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxPriorReduxPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HiDreamImagePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanDiTControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanDiTPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanDiTPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanSkyreelsImageToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanVideoFramepackPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanVideoImageToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class I2VGenXLPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class IFImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class IFImg2ImgSuperResolutionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class IFInpaintingPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class IFInpaintingSuperResolutionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class IFPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class IFSuperResolutionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class ImageTextPipelineOutput(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class Kandinsky3Img2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class Kandinsky3Pipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyImg2ImgCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyInpaintCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyPriorPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22CombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22ControlnetImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22ControlnetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22Img2ImgCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22Img2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22InpaintCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22InpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22Pipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22PriorEmb2EmbPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22PriorPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LatentConsistencyModelImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LatentConsistencyModelPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LattePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LDMTextToImagePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LEditsPPPipelineStableDiffusion(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LEditsPPPipelineStableDiffusionXL(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LTXConditionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LTXImageToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LTXLatentUpsamplePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LTXPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class Lumina2Pipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class Lumina2Text2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LuminaPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LuminaText2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class MarigoldDepthPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class MarigoldIntrinsicsPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class MarigoldNormalsPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class MochiPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class MusicLDMPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class OmniGenPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class PaintByExamplePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class PIAPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class PixArtAlphaPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class PixArtSigmaPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class PixArtSigmaPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class ReduxImageEncoder(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class SanaControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class SanaPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class SanaPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class SanaSprintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class SemanticStableDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class ShapEImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class ShapEPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableAudioPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableAudioProjectionModel(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableCascadeCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableCascadeDecoderPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableCascadePriorPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3ControlNetInpaintingPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3ControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3Img2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3InpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3PAGImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3PAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3Pipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionAdapterPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionAttendAndExcitePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionControlNetImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionControlNetInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionControlNetPAGInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionControlNetPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionControlNetXSPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionDepth2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionDiffEditPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionGLIGENPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionGLIGENTextImagePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionImageVariationPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionInpaintPipelineLegacy(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionInstructPix2PixPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionLatentUpscalePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionLDM3DPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionModelEditingPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPAGImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPAGInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPanoramaPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionParadigmsPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPipelineSafe(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPix2PixZeroPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionSAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionUpscalePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLAdapterPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetPAGImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetUnionImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetUnionInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetUnionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetXSPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLInstructPix2PixPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLPAGImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLPAGInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableUnCLIPImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableUnCLIPPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableVideoDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class TextToVideoSDPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class TextToVideoZeroPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class TextToVideoZeroSDXLPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class UnCLIPImageVariationPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class UnCLIPPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class UniDiffuserModel(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class UniDiffuserPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class UniDiffuserTextDecoder(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VersatileDiffusionDualGuidedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VersatileDiffusionImageVariationPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VersatileDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VersatileDiffusionTextToImagePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VideoToVideoSDPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VisualClozeGenerationPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VisualClozePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VQDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class WanImageToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class WanPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class WanVideoToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class WuerstchenCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class WuerstchenDecoderPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class WuerstchenPriorPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torchao_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torchao_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..16f0f6a55f64099c73ce4d81af8c87053b833e44 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_torchao_objects.py @@ -0,0 +1,17 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class TorchAoConfig(metaclass=DummyObject): + _backends = ["torchao"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torchao"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torchao"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torchao"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_transformers_and_torch_and_note_seq_objects.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_transformers_and_torch_and_note_seq_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..fbde04e33f0abd86d12f3dee048a4f0585c9f19d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dummy_transformers_and_torch_and_note_seq_objects.py @@ -0,0 +1,17 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class SpectrogramDiffusionPipeline(metaclass=DummyObject): + _backends = ["transformers", "torch", "note_seq"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["transformers", "torch", "note_seq"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["transformers", "torch", "note_seq"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["transformers", "torch", "note_seq"]) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dynamic_modules_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dynamic_modules_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..5d0752af8983f58267064e60feef76629280230c --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/dynamic_modules_utils.py @@ -0,0 +1,457 @@ +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Utilities to dynamically load objects from the Hub.""" + +import importlib +import inspect +import json +import os +import re +import shutil +import sys +from pathlib import Path +from typing import Dict, Optional, Union +from urllib import request + +from huggingface_hub import hf_hub_download, model_info +from huggingface_hub.utils import RevisionNotFoundError, validate_hf_hub_args +from packaging import version + +from .. import __version__ +from . import DIFFUSERS_DYNAMIC_MODULE_NAME, HF_MODULES_CACHE, logging + + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + +# See https://huggingface.co/datasets/diffusers/community-pipelines-mirror +COMMUNITY_PIPELINES_MIRROR_ID = "diffusers/community-pipelines-mirror" + + +def get_diffusers_versions(): + url = "https://pypi.org/pypi/diffusers/json" + releases = json.loads(request.urlopen(url).read())["releases"].keys() + return sorted(releases, key=lambda x: version.Version(x)) + + +def init_hf_modules(): + """ + Creates the cache directory for modules with an init, and adds it to the Python path. + """ + # This function has already been executed if HF_MODULES_CACHE already is in the Python path. + if HF_MODULES_CACHE in sys.path: + return + + sys.path.append(HF_MODULES_CACHE) + os.makedirs(HF_MODULES_CACHE, exist_ok=True) + init_path = Path(HF_MODULES_CACHE) / "__init__.py" + if not init_path.exists(): + init_path.touch() + + +def create_dynamic_module(name: Union[str, os.PathLike]): + """ + Creates a dynamic module in the cache directory for modules. + """ + init_hf_modules() + dynamic_module_path = Path(HF_MODULES_CACHE) / name + # If the parent module does not exist yet, recursively create it. + if not dynamic_module_path.parent.exists(): + create_dynamic_module(dynamic_module_path.parent) + os.makedirs(dynamic_module_path, exist_ok=True) + init_path = dynamic_module_path / "__init__.py" + if not init_path.exists(): + init_path.touch() + + +def get_relative_imports(module_file): + """ + Get the list of modules that are relatively imported in a module file. + + Args: + module_file (`str` or `os.PathLike`): The module file to inspect. + """ + with open(module_file, "r", encoding="utf-8") as f: + content = f.read() + + # Imports of the form `import .xxx` + relative_imports = re.findall(r"^\s*import\s+\.(\S+)\s*$", content, flags=re.MULTILINE) + # Imports of the form `from .xxx import yyy` + relative_imports += re.findall(r"^\s*from\s+\.(\S+)\s+import", content, flags=re.MULTILINE) + # Unique-ify + return list(set(relative_imports)) + + +def get_relative_import_files(module_file): + """ + Get the list of all files that are needed for a given module. Note that this function recurses through the relative + imports (if a imports b and b imports c, it will return module files for b and c). + + Args: + module_file (`str` or `os.PathLike`): The module file to inspect. + """ + no_change = False + files_to_check = [module_file] + all_relative_imports = [] + + # Let's recurse through all relative imports + while not no_change: + new_imports = [] + for f in files_to_check: + new_imports.extend(get_relative_imports(f)) + + module_path = Path(module_file).parent + new_import_files = [str(module_path / m) for m in new_imports] + new_import_files = [f for f in new_import_files if f not in all_relative_imports] + files_to_check = [f"{f}.py" for f in new_import_files] + + no_change = len(new_import_files) == 0 + all_relative_imports.extend(files_to_check) + + return all_relative_imports + + +def check_imports(filename): + """ + Check if the current Python environment contains all the libraries that are imported in a file. + """ + with open(filename, "r", encoding="utf-8") as f: + content = f.read() + + # Imports of the form `import xxx` + imports = re.findall(r"^\s*import\s+(\S+)\s*$", content, flags=re.MULTILINE) + # Imports of the form `from xxx import yyy` + imports += re.findall(r"^\s*from\s+(\S+)\s+import", content, flags=re.MULTILINE) + # Only keep the top-level module + imports = [imp.split(".")[0] for imp in imports if not imp.startswith(".")] + + # Unique-ify and test we got them all + imports = list(set(imports)) + missing_packages = [] + for imp in imports: + try: + importlib.import_module(imp) + except ImportError: + missing_packages.append(imp) + + if len(missing_packages) > 0: + raise ImportError( + "This modeling file requires the following packages that were not found in your environment: " + f"{', '.join(missing_packages)}. Run `pip install {' '.join(missing_packages)}`" + ) + + return get_relative_imports(filename) + + +def get_class_in_module(class_name, module_path): + """ + Import a module on the cache directory for modules and extract a class from it. + """ + module_path = module_path.replace(os.path.sep, ".") + module = importlib.import_module(module_path) + + if class_name is None: + return find_pipeline_class(module) + return getattr(module, class_name) + + +def find_pipeline_class(loaded_module): + """ + Retrieve pipeline class that inherits from `DiffusionPipeline`. Note that there has to be exactly one class + inheriting from `DiffusionPipeline`. + """ + from ..pipelines import DiffusionPipeline + + cls_members = dict(inspect.getmembers(loaded_module, inspect.isclass)) + + pipeline_class = None + for cls_name, cls in cls_members.items(): + if ( + cls_name != DiffusionPipeline.__name__ + and issubclass(cls, DiffusionPipeline) + and cls.__module__.split(".")[0] != "diffusers" + ): + if pipeline_class is not None: + raise ValueError( + f"Multiple classes that inherit from {DiffusionPipeline.__name__} have been found:" + f" {pipeline_class.__name__}, and {cls_name}. Please make sure to define only one in" + f" {loaded_module}." + ) + pipeline_class = cls + + return pipeline_class + + +@validate_hf_hub_args +def get_cached_module_file( + pretrained_model_name_or_path: Union[str, os.PathLike], + module_file: str, + cache_dir: Optional[Union[str, os.PathLike]] = None, + force_download: bool = False, + proxies: Optional[Dict[str, str]] = None, + token: Optional[Union[bool, str]] = None, + revision: Optional[str] = None, + local_files_only: bool = False, +): + """ + Prepares Downloads a module from a local folder or a distant repo and returns its path inside the cached + Transformers module. + + Args: + pretrained_model_name_or_path (`str` or `os.PathLike`): + This can be either: + + - a string, the *model id* of a pretrained model configuration hosted inside a model repo on + huggingface.co. Valid model ids can be located at the root-level, like `bert-base-uncased`, or namespaced + under a user or organization name, like `dbmdz/bert-base-german-cased`. + - a path to a *directory* containing a configuration file saved using the + [`~PreTrainedTokenizer.save_pretrained`] method, e.g., `./my_model_directory/`. + + module_file (`str`): + The name of the module file containing the class to look for. + cache_dir (`str` or `os.PathLike`, *optional*): + Path to a directory in which a downloaded pretrained model configuration should be cached if the standard + cache should not be used. + force_download (`bool`, *optional*, defaults to `False`): + Whether or not to force to (re-)download the configuration files and override the cached versions if they + exist. + proxies (`Dict[str, str]`, *optional*): + A dictionary of proxy servers to use by protocol or endpoint, e.g., `{'http': 'foo.bar:3128', + 'http://hostname': 'foo.bar:4012'}.` The proxies are used on each request. + token (`str` or *bool*, *optional*): + The token to use as HTTP bearer authorization for remote files. If `True`, will use the token generated + when running `transformers-cli login` (stored in `~/.huggingface`). + revision (`str`, *optional*, defaults to `"main"`): + The specific model version to use. It can be a branch name, a tag name, or a commit id, since we use a + git-based system for storing models and other artifacts on huggingface.co, so `revision` can be any + identifier allowed by git. + local_files_only (`bool`, *optional*, defaults to `False`): + If `True`, will only try to load the tokenizer configuration from local files. + + + + You may pass a token in `token` if you are not logged in (`huggingface-cli login`) and want to use private or + [gated models](https://huggingface.co/docs/hub/models-gated#gated-models). + + + + Returns: + `str`: The path to the module inside the cache. + """ + # Download and cache module_file from the repo `pretrained_model_name_or_path` of grab it if it's a local file. + pretrained_model_name_or_path = str(pretrained_model_name_or_path) + + module_file_or_url = os.path.join(pretrained_model_name_or_path, module_file) + + if os.path.isfile(module_file_or_url): + resolved_module_file = module_file_or_url + submodule = "local" + elif pretrained_model_name_or_path.count("/") == 0: + available_versions = get_diffusers_versions() + # cut ".dev0" + latest_version = "v" + ".".join(__version__.split(".")[:3]) + + # retrieve github version that matches + if revision is None: + revision = latest_version if latest_version[1:] in available_versions else "main" + logger.info(f"Defaulting to latest_version: {revision}.") + elif revision in available_versions: + revision = f"v{revision}" + elif revision == "main": + revision = revision + else: + raise ValueError( + f"`custom_revision`: {revision} does not exist. Please make sure to choose one of" + f" {', '.join(available_versions + ['main'])}." + ) + + try: + resolved_module_file = hf_hub_download( + repo_id=COMMUNITY_PIPELINES_MIRROR_ID, + repo_type="dataset", + filename=f"{revision}/{pretrained_model_name_or_path}.py", + cache_dir=cache_dir, + force_download=force_download, + proxies=proxies, + local_files_only=local_files_only, + ) + submodule = "git" + module_file = pretrained_model_name_or_path + ".py" + except RevisionNotFoundError as e: + raise EnvironmentError( + f"Revision '{revision}' not found in the community pipelines mirror. Check available revisions on" + " https://huggingface.co/datasets/diffusers/community-pipelines-mirror/tree/main." + " If you don't find the revision you are looking for, please open an issue on https://github.com/huggingface/diffusers/issues." + ) from e + except EnvironmentError: + logger.error(f"Could not locate the {module_file} inside {pretrained_model_name_or_path}.") + raise + else: + try: + # Load from URL or cache if already cached + resolved_module_file = hf_hub_download( + pretrained_model_name_or_path, + module_file, + cache_dir=cache_dir, + force_download=force_download, + proxies=proxies, + local_files_only=local_files_only, + token=token, + ) + submodule = os.path.join("local", "--".join(pretrained_model_name_or_path.split("/"))) + except EnvironmentError: + logger.error(f"Could not locate the {module_file} inside {pretrained_model_name_or_path}.") + raise + + # Check we have all the requirements in our environment + modules_needed = check_imports(resolved_module_file) + + # Now we move the module inside our cached dynamic modules. + full_submodule = DIFFUSERS_DYNAMIC_MODULE_NAME + os.path.sep + submodule + create_dynamic_module(full_submodule) + submodule_path = Path(HF_MODULES_CACHE) / full_submodule + if submodule == "local" or submodule == "git": + # We always copy local files (we could hash the file to see if there was a change, and give them the name of + # that hash, to only copy when there is a modification but it seems overkill for now). + # The only reason we do the copy is to avoid putting too many folders in sys.path. + shutil.copyfile(resolved_module_file, submodule_path / module_file) + for module_needed in modules_needed: + if len(module_needed.split(".")) == 2: + module_needed = "/".join(module_needed.split(".")) + module_folder = module_needed.split("/")[0] + if not os.path.exists(submodule_path / module_folder): + os.makedirs(submodule_path / module_folder) + module_needed = f"{module_needed}.py" + shutil.copyfile(os.path.join(pretrained_model_name_or_path, module_needed), submodule_path / module_needed) + else: + # Get the commit hash + # TODO: we will get this info in the etag soon, so retrieve it from there and not here. + commit_hash = model_info(pretrained_model_name_or_path, revision=revision, token=token).sha + + # The module file will end up being placed in a subfolder with the git hash of the repo. This way we get the + # benefit of versioning. + submodule_path = submodule_path / commit_hash + full_submodule = full_submodule + os.path.sep + commit_hash + create_dynamic_module(full_submodule) + + if not (submodule_path / module_file).exists(): + if len(module_file.split("/")) == 2: + module_folder = module_file.split("/")[0] + if not os.path.exists(submodule_path / module_folder): + os.makedirs(submodule_path / module_folder) + shutil.copyfile(resolved_module_file, submodule_path / module_file) + + # Make sure we also have every file with relative + for module_needed in modules_needed: + if len(module_needed.split(".")) == 2: + module_needed = "/".join(module_needed.split(".")) + if not (submodule_path / module_needed).exists(): + get_cached_module_file( + pretrained_model_name_or_path, + f"{module_needed}.py", + cache_dir=cache_dir, + force_download=force_download, + proxies=proxies, + token=token, + revision=revision, + local_files_only=local_files_only, + ) + return os.path.join(full_submodule, module_file) + + +@validate_hf_hub_args +def get_class_from_dynamic_module( + pretrained_model_name_or_path: Union[str, os.PathLike], + module_file: str, + class_name: Optional[str] = None, + cache_dir: Optional[Union[str, os.PathLike]] = None, + force_download: bool = False, + proxies: Optional[Dict[str, str]] = None, + token: Optional[Union[bool, str]] = None, + revision: Optional[str] = None, + local_files_only: bool = False, + **kwargs, +): + """ + Extracts a class from a module file, present in the local folder or repository of a model. + + + + Calling this function will execute the code in the module file found locally or downloaded from the Hub. It should + therefore only be called on trusted repos. + + + + Args: + pretrained_model_name_or_path (`str` or `os.PathLike`): + This can be either: + + - a string, the *model id* of a pretrained model configuration hosted inside a model repo on + huggingface.co. Valid model ids can be located at the root-level, like `bert-base-uncased`, or namespaced + under a user or organization name, like `dbmdz/bert-base-german-cased`. + - a path to a *directory* containing a configuration file saved using the + [`~PreTrainedTokenizer.save_pretrained`] method, e.g., `./my_model_directory/`. + + module_file (`str`): + The name of the module file containing the class to look for. + class_name (`str`): + The name of the class to import in the module. + cache_dir (`str` or `os.PathLike`, *optional*): + Path to a directory in which a downloaded pretrained model configuration should be cached if the standard + cache should not be used. + force_download (`bool`, *optional*, defaults to `False`): + Whether or not to force to (re-)download the configuration files and override the cached versions if they + exist. + proxies (`Dict[str, str]`, *optional*): + A dictionary of proxy servers to use by protocol or endpoint, e.g., `{'http': 'foo.bar:3128', + 'http://hostname': 'foo.bar:4012'}.` The proxies are used on each request. + token (`str` or `bool`, *optional*): + The token to use as HTTP bearer authorization for remote files. If `True`, will use the token generated + when running `transformers-cli login` (stored in `~/.huggingface`). + revision (`str`, *optional*, defaults to `"main"`): + The specific model version to use. It can be a branch name, a tag name, or a commit id, since we use a + git-based system for storing models and other artifacts on huggingface.co, so `revision` can be any + identifier allowed by git. + local_files_only (`bool`, *optional*, defaults to `False`): + If `True`, will only try to load the tokenizer configuration from local files. + + + + You may pass a token in `token` if you are not logged in (`huggingface-cli login`) and want to use private or + [gated models](https://huggingface.co/docs/hub/models-gated#gated-models). + + + + Returns: + `type`: The class, dynamically imported from the module. + + Examples: + + ```python + # Download module `modeling.py` from huggingface.co and cache then extract the class `MyBertModel` from this + # module. + cls = get_class_from_dynamic_module("sgugger/my-bert-model", "modeling.py", "MyBertModel") + ```""" + # And lastly we get the class inside our newly created module + final_module = get_cached_module_file( + pretrained_model_name_or_path, + module_file, + cache_dir=cache_dir, + force_download=force_download, + proxies=proxies, + token=token, + revision=revision, + local_files_only=local_files_only, + ) + return get_class_in_module(class_name, final_module.replace(".py", "")) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/export_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/export_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..07cf46928a44df0b27337e5d007c6a9bdb0e7c28 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/export_utils.py @@ -0,0 +1,209 @@ +import io +import random +import struct +import tempfile +from contextlib import contextmanager +from typing import List, Optional, Union + +import numpy as np +import PIL.Image +import PIL.ImageOps + +from .import_utils import BACKENDS_MAPPING, is_imageio_available, is_opencv_available +from .logging import get_logger + + +global_rng = random.Random() + +logger = get_logger(__name__) + + +@contextmanager +def buffered_writer(raw_f): + f = io.BufferedWriter(raw_f) + yield f + f.flush() + + +def export_to_gif(image: List[PIL.Image.Image], output_gif_path: str = None, fps: int = 10) -> str: + if output_gif_path is None: + output_gif_path = tempfile.NamedTemporaryFile(suffix=".gif").name + + image[0].save( + output_gif_path, + save_all=True, + append_images=image[1:], + optimize=False, + duration=1000 // fps, + loop=0, + ) + return output_gif_path + + +def export_to_ply(mesh, output_ply_path: str = None): + """ + Write a PLY file for a mesh. + """ + if output_ply_path is None: + output_ply_path = tempfile.NamedTemporaryFile(suffix=".ply").name + + coords = mesh.verts.detach().cpu().numpy() + faces = mesh.faces.cpu().numpy() + rgb = np.stack([mesh.vertex_channels[x].detach().cpu().numpy() for x in "RGB"], axis=1) + + with buffered_writer(open(output_ply_path, "wb")) as f: + f.write(b"ply\n") + f.write(b"format binary_little_endian 1.0\n") + f.write(bytes(f"element vertex {len(coords)}\n", "ascii")) + f.write(b"property float x\n") + f.write(b"property float y\n") + f.write(b"property float z\n") + if rgb is not None: + f.write(b"property uchar red\n") + f.write(b"property uchar green\n") + f.write(b"property uchar blue\n") + if faces is not None: + f.write(bytes(f"element face {len(faces)}\n", "ascii")) + f.write(b"property list uchar int vertex_index\n") + f.write(b"end_header\n") + + if rgb is not None: + rgb = (rgb * 255.499).round().astype(int) + vertices = [ + (*coord, *rgb) + for coord, rgb in zip( + coords.tolist(), + rgb.tolist(), + ) + ] + format = struct.Struct("<3f3B") + for item in vertices: + f.write(format.pack(*item)) + else: + format = struct.Struct("<3f") + for vertex in coords.tolist(): + f.write(format.pack(*vertex)) + + if faces is not None: + format = struct.Struct(" str: + """ + quality: + Video output quality. Default is 5. Uses variable bit rate. Highest quality is 10, lowest is 0. Set to None to + prevent variable bitrate flags to FFMPEG so you can manually specify them using output_params instead. + Specifying a fixed bitrate using `bitrate` disables this parameter. + + bitrate: + Set a constant bitrate for the video encoding. Default is None causing `quality` parameter to be used instead. + Better quality videos with smaller file sizes will result from using the `quality` variable bitrate parameter + rather than specifying a fixed bitrate with this parameter. + + macro_block_size: + Size constraint for video. Width and height, must be divisible by this number. If not divisible by this number + imageio will tell ffmpeg to scale the image up to the next closest size divisible by this number. Most codecs + are compatible with a macroblock size of 16 (default), some can go smaller (4, 8). To disable this automatic + feature set it to None or 1, however be warned many players can't decode videos that are odd in size and some + codecs will produce poor results or fail. See https://en.wikipedia.org/wiki/Macroblock. + """ + # TODO: Dhruv. Remove by Diffusers release 0.33.0 + # Added to prevent breaking existing code + if not is_imageio_available(): + logger.warning( + ( + "It is recommended to use `export_to_video` with `imageio` and `imageio-ffmpeg` as a backend. \n" + "These libraries are not present in your environment. Attempting to use legacy OpenCV backend to export video. \n" + "Support for the OpenCV backend will be deprecated in a future Diffusers version" + ) + ) + return _legacy_export_to_video(video_frames, output_video_path, fps) + + if is_imageio_available(): + import imageio + else: + raise ImportError(BACKENDS_MAPPING["imageio"][1].format("export_to_video")) + + try: + imageio.plugins.ffmpeg.get_exe() + except AttributeError: + raise AttributeError( + ( + "Found an existing imageio backend in your environment. Attempting to export video with imageio. \n" + "Unable to find a compatible ffmpeg installation in your environment to use with imageio. Please install via `pip install imageio-ffmpeg" + ) + ) + + if output_video_path is None: + output_video_path = tempfile.NamedTemporaryFile(suffix=".mp4").name + + if isinstance(video_frames[0], np.ndarray): + video_frames = [(frame * 255).astype(np.uint8) for frame in video_frames] + + elif isinstance(video_frames[0], PIL.Image.Image): + video_frames = [np.array(frame) for frame in video_frames] + + with imageio.get_writer( + output_video_path, fps=fps, quality=quality, bitrate=bitrate, macro_block_size=macro_block_size + ) as writer: + for frame in video_frames: + writer.append_data(frame) + + return output_video_path diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/hub_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/hub_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..f80f96a3425d880c54bcf95d65dc6f3d2ba0f312 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/hub_utils.py @@ -0,0 +1,557 @@ +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +import json +import os +import re +import sys +import tempfile +import warnings +from pathlib import Path +from typing import Dict, List, Optional, Union +from uuid import uuid4 + +from huggingface_hub import ( + DDUFEntry, + ModelCard, + ModelCardData, + create_repo, + hf_hub_download, + model_info, + snapshot_download, + upload_folder, +) +from huggingface_hub.constants import HF_HUB_DISABLE_TELEMETRY, HF_HUB_OFFLINE +from huggingface_hub.file_download import REGEX_COMMIT_HASH +from huggingface_hub.utils import ( + EntryNotFoundError, + RepositoryNotFoundError, + RevisionNotFoundError, + is_jinja_available, + validate_hf_hub_args, +) +from packaging import version +from requests import HTTPError + +from .. import __version__ +from .constants import ( + DEPRECATED_REVISION_ARGS, + HUGGINGFACE_CO_RESOLVE_ENDPOINT, + SAFETENSORS_WEIGHTS_NAME, + WEIGHTS_NAME, +) +from .import_utils import ( + ENV_VARS_TRUE_VALUES, + _flax_version, + _jax_version, + _onnxruntime_version, + _torch_version, + is_flax_available, + is_onnx_available, + is_torch_available, +) +from .logging import get_logger + + +logger = get_logger(__name__) + +MODEL_CARD_TEMPLATE_PATH = Path(__file__).parent / "model_card_template.md" +SESSION_ID = uuid4().hex + + +def http_user_agent(user_agent: Union[Dict, str, None] = None) -> str: + """ + Formats a user-agent string with basic info about a request. + """ + ua = f"diffusers/{__version__}; python/{sys.version.split()[0]}; session_id/{SESSION_ID}" + if HF_HUB_DISABLE_TELEMETRY or HF_HUB_OFFLINE: + return ua + "; telemetry/off" + if is_torch_available(): + ua += f"; torch/{_torch_version}" + if is_flax_available(): + ua += f"; jax/{_jax_version}" + ua += f"; flax/{_flax_version}" + if is_onnx_available(): + ua += f"; onnxruntime/{_onnxruntime_version}" + # CI will set this value to True + if os.environ.get("DIFFUSERS_IS_CI", "").upper() in ENV_VARS_TRUE_VALUES: + ua += "; is_ci/true" + if isinstance(user_agent, dict): + ua += "; " + "; ".join(f"{k}/{v}" for k, v in user_agent.items()) + elif isinstance(user_agent, str): + ua += "; " + user_agent + return ua + + +def load_or_create_model_card( + repo_id_or_path: str = None, + token: Optional[str] = None, + is_pipeline: bool = False, + from_training: bool = False, + model_description: Optional[str] = None, + base_model: str = None, + prompt: Optional[str] = None, + license: Optional[str] = None, + widget: Optional[List[dict]] = None, + inference: Optional[bool] = None, +) -> ModelCard: + """ + Loads or creates a model card. + + Args: + repo_id_or_path (`str`): + The repo id (e.g., "runwayml/stable-diffusion-v1-5") or local path where to look for the model card. + token (`str`, *optional*): + Authentication token. Will default to the stored token. See https://huggingface.co/settings/token for more + details. + is_pipeline (`bool`): + Boolean to indicate if we're adding tag to a [`DiffusionPipeline`]. + from_training: (`bool`): Boolean flag to denote if the model card is being created from a training script. + model_description (`str`, *optional*): Model description to add to the model card. Helpful when using + `load_or_create_model_card` from a training script. + base_model (`str`): Base model identifier (e.g., "stabilityai/stable-diffusion-xl-base-1.0"). Useful + for DreamBooth-like training. + prompt (`str`, *optional*): Prompt used for training. Useful for DreamBooth-like training. + license: (`str`, *optional*): License of the output artifact. Helpful when using + `load_or_create_model_card` from a training script. + widget (`List[dict]`, *optional*): Widget to accompany a gallery template. + inference: (`bool`, optional): Whether to turn on inference widget. Helpful when using + `load_or_create_model_card` from a training script. + """ + if not is_jinja_available(): + raise ValueError( + "Modelcard rendering is based on Jinja templates." + " Please make sure to have `jinja` installed before using `load_or_create_model_card`." + " To install it, please run `pip install Jinja2`." + ) + + try: + # Check if the model card is present on the remote repo + model_card = ModelCard.load(repo_id_or_path, token=token) + except (EntryNotFoundError, RepositoryNotFoundError): + # Otherwise create a model card from template + if from_training: + model_card = ModelCard.from_template( + card_data=ModelCardData( # Card metadata object that will be converted to YAML block + license=license, + library_name="diffusers", + inference=inference, + base_model=base_model, + instance_prompt=prompt, + widget=widget, + ), + template_path=MODEL_CARD_TEMPLATE_PATH, + model_description=model_description, + ) + else: + card_data = ModelCardData() + component = "pipeline" if is_pipeline else "model" + if model_description is None: + model_description = f"This is the model card of a 🧨 diffusers {component} that has been pushed on the Hub. This model card has been automatically generated." + model_card = ModelCard.from_template(card_data, model_description=model_description) + + return model_card + + +def populate_model_card(model_card: ModelCard, tags: Union[str, List[str]] = None) -> ModelCard: + """Populates the `model_card` with library name and optional tags.""" + if model_card.data.library_name is None: + model_card.data.library_name = "diffusers" + + if tags is not None: + if isinstance(tags, str): + tags = [tags] + if model_card.data.tags is None: + model_card.data.tags = [] + for tag in tags: + model_card.data.tags.append(tag) + + return model_card + + +def extract_commit_hash(resolved_file: Optional[str], commit_hash: Optional[str] = None): + """ + Extracts the commit hash from a resolved filename toward a cache file. + """ + if resolved_file is None or commit_hash is not None: + return commit_hash + resolved_file = str(Path(resolved_file).as_posix()) + search = re.search(r"snapshots/([^/]+)/", resolved_file) + if search is None: + return None + commit_hash = search.groups()[0] + return commit_hash if REGEX_COMMIT_HASH.match(commit_hash) else None + + +def _add_variant(weights_name: str, variant: Optional[str] = None) -> str: + if variant is not None: + splits = weights_name.split(".") + splits = splits[:-1] + [variant] + splits[-1:] + weights_name = ".".join(splits) + + return weights_name + + +@validate_hf_hub_args +def _get_model_file( + pretrained_model_name_or_path: Union[str, Path], + *, + weights_name: str, + subfolder: Optional[str] = None, + cache_dir: Optional[str] = None, + force_download: bool = False, + proxies: Optional[Dict] = None, + local_files_only: bool = False, + token: Optional[str] = None, + user_agent: Optional[Union[Dict, str]] = None, + revision: Optional[str] = None, + commit_hash: Optional[str] = None, + dduf_entries: Optional[Dict[str, DDUFEntry]] = None, +): + pretrained_model_name_or_path = str(pretrained_model_name_or_path) + + if dduf_entries: + if subfolder is not None: + raise ValueError( + "DDUF file only allow for 1 level of directory (e.g transformer/model1/model.safetentors is not allowed). " + "Please check the DDUF structure" + ) + model_file = ( + weights_name + if pretrained_model_name_or_path == "" + else "/".join([pretrained_model_name_or_path, weights_name]) + ) + if model_file in dduf_entries: + return model_file + else: + raise EnvironmentError(f"Error no file named {weights_name} found in archive {dduf_entries.keys()}.") + elif os.path.isfile(pretrained_model_name_or_path): + return pretrained_model_name_or_path + elif os.path.isdir(pretrained_model_name_or_path): + if os.path.isfile(os.path.join(pretrained_model_name_or_path, weights_name)): + # Load from a PyTorch checkpoint + model_file = os.path.join(pretrained_model_name_or_path, weights_name) + return model_file + elif subfolder is not None and os.path.isfile( + os.path.join(pretrained_model_name_or_path, subfolder, weights_name) + ): + model_file = os.path.join(pretrained_model_name_or_path, subfolder, weights_name) + return model_file + else: + raise EnvironmentError( + f"Error no file named {weights_name} found in directory {pretrained_model_name_or_path}." + ) + else: + # 1. First check if deprecated way of loading from branches is used + if ( + revision in DEPRECATED_REVISION_ARGS + and (weights_name == WEIGHTS_NAME or weights_name == SAFETENSORS_WEIGHTS_NAME) + and version.parse(version.parse(__version__).base_version) >= version.parse("0.22.0") + ): + try: + model_file = hf_hub_download( + pretrained_model_name_or_path, + filename=_add_variant(weights_name, revision), + cache_dir=cache_dir, + force_download=force_download, + proxies=proxies, + local_files_only=local_files_only, + token=token, + user_agent=user_agent, + subfolder=subfolder, + revision=revision or commit_hash, + ) + warnings.warn( + f"Loading the variant {revision} from {pretrained_model_name_or_path} via `revision='{revision}'` is deprecated. Loading instead from `revision='main'` with `variant={revision}`. Loading model variants via `revision='{revision}'` will be removed in diffusers v1. Please use `variant='{revision}'` instead.", + FutureWarning, + ) + return model_file + except: # noqa: E722 + warnings.warn( + f"You are loading the variant {revision} from {pretrained_model_name_or_path} via `revision='{revision}'`. This behavior is deprecated and will be removed in diffusers v1. One should use `variant='{revision}'` instead. However, it appears that {pretrained_model_name_or_path} currently does not have a {_add_variant(weights_name, revision)} file in the 'main' branch of {pretrained_model_name_or_path}. \n The Diffusers team and community would be very grateful if you could open an issue: https://github.com/huggingface/diffusers/issues/new with the title '{pretrained_model_name_or_path} is missing {_add_variant(weights_name, revision)}' so that the correct variant file can be added.", + FutureWarning, + ) + try: + # 2. Load model file as usual + model_file = hf_hub_download( + pretrained_model_name_or_path, + filename=weights_name, + cache_dir=cache_dir, + force_download=force_download, + proxies=proxies, + local_files_only=local_files_only, + token=token, + user_agent=user_agent, + subfolder=subfolder, + revision=revision or commit_hash, + ) + return model_file + + except RepositoryNotFoundError as e: + raise EnvironmentError( + f"{pretrained_model_name_or_path} is not a local folder and is not a valid model identifier " + "listed on 'https://huggingface.co/models'\nIf this is a private repository, make sure to pass a " + "token having permission to this repo with `token` or log in with `huggingface-cli " + "login`." + ) from e + except RevisionNotFoundError as e: + raise EnvironmentError( + f"{revision} is not a valid git identifier (branch name, tag name or commit id) that exists for " + "this model name. Check the model page at " + f"'https://huggingface.co/{pretrained_model_name_or_path}' for available revisions." + ) from e + except EntryNotFoundError as e: + raise EnvironmentError( + f"{pretrained_model_name_or_path} does not appear to have a file named {weights_name}." + ) from e + except HTTPError as e: + raise EnvironmentError( + f"There was a specific connection error when trying to load {pretrained_model_name_or_path}:\n{e}" + ) from e + except ValueError as e: + raise EnvironmentError( + f"We couldn't connect to '{HUGGINGFACE_CO_RESOLVE_ENDPOINT}' to load this model, couldn't find it" + f" in the cached files and it looks like {pretrained_model_name_or_path} is not the path to a" + f" directory containing a file named {weights_name} or" + " \nCheckout your internet connection or see how to run the library in" + " offline mode at 'https://huggingface.co/docs/diffusers/installation#offline-mode'." + ) from e + except EnvironmentError as e: + raise EnvironmentError( + f"Can't load the model for '{pretrained_model_name_or_path}'. If you were trying to load it from " + "'https://huggingface.co/models', make sure you don't have a local directory with the same name. " + f"Otherwise, make sure '{pretrained_model_name_or_path}' is the correct path to a directory " + f"containing a file named {weights_name}" + ) from e + + +def _get_checkpoint_shard_files( + pretrained_model_name_or_path, + index_filename, + cache_dir=None, + proxies=None, + local_files_only=False, + token=None, + user_agent=None, + revision=None, + subfolder="", + dduf_entries: Optional[Dict[str, DDUFEntry]] = None, +): + """ + For a given model: + + - download and cache all the shards of a sharded checkpoint if `pretrained_model_name_or_path` is a model ID on the + Hub + - returns the list of paths to all the shards, as well as some metadata. + + For the description of each arg, see [`PreTrainedModel.from_pretrained`]. `index_filename` is the full path to the + index (downloaded and cached if `pretrained_model_name_or_path` is a model ID on the Hub). + """ + if dduf_entries: + if index_filename not in dduf_entries: + raise ValueError(f"Can't find a checkpoint index ({index_filename}) in {pretrained_model_name_or_path}.") + else: + if not os.path.isfile(index_filename): + raise ValueError(f"Can't find a checkpoint index ({index_filename}) in {pretrained_model_name_or_path}.") + + if dduf_entries: + index = json.loads(dduf_entries[index_filename].read_text()) + else: + with open(index_filename, "r") as f: + index = json.loads(f.read()) + + original_shard_filenames = sorted(set(index["weight_map"].values())) + sharded_metadata = index["metadata"] + sharded_metadata["all_checkpoint_keys"] = list(index["weight_map"].keys()) + sharded_metadata["weight_map"] = index["weight_map"].copy() + shards_path = os.path.join(pretrained_model_name_or_path, subfolder) + + # First, let's deal with local folder. + if os.path.isdir(pretrained_model_name_or_path) or dduf_entries: + shard_filenames = [os.path.join(shards_path, f) for f in original_shard_filenames] + for shard_file in shard_filenames: + if dduf_entries: + if shard_file not in dduf_entries: + raise FileNotFoundError( + f"{shards_path} does not appear to have a file named {shard_file} which is " + "required according to the checkpoint index." + ) + else: + if not os.path.exists(shard_file): + raise FileNotFoundError( + f"{shards_path} does not appear to have a file named {shard_file} which is " + "required according to the checkpoint index." + ) + return shard_filenames, sharded_metadata + + # At this stage pretrained_model_name_or_path is a model identifier on the Hub + allow_patterns = original_shard_filenames + if subfolder is not None: + allow_patterns = [os.path.join(subfolder, p) for p in allow_patterns] + + ignore_patterns = ["*.json", "*.md"] + # `model_info` call must guarded with the above condition. + model_files_info = model_info(pretrained_model_name_or_path, revision=revision, token=token) + for shard_file in original_shard_filenames: + shard_file_present = any(shard_file in k.rfilename for k in model_files_info.siblings) + if not shard_file_present: + raise EnvironmentError( + f"{shards_path} does not appear to have a file named {shard_file} which is " + "required according to the checkpoint index." + ) + + try: + # Load from URL + cached_folder = snapshot_download( + pretrained_model_name_or_path, + cache_dir=cache_dir, + proxies=proxies, + local_files_only=local_files_only, + token=token, + revision=revision, + allow_patterns=allow_patterns, + ignore_patterns=ignore_patterns, + user_agent=user_agent, + ) + if subfolder is not None: + cached_folder = os.path.join(cached_folder, subfolder) + + # We have already dealt with RepositoryNotFoundError and RevisionNotFoundError when getting the index, so + # we don't have to catch them here. We have also dealt with EntryNotFoundError. + except HTTPError as e: + raise EnvironmentError( + f"We couldn't connect to '{HUGGINGFACE_CO_RESOLVE_ENDPOINT}' to load {pretrained_model_name_or_path}. You should try" + " again after checking your internet connection." + ) from e + + cached_filenames = [os.path.join(cached_folder, f) for f in original_shard_filenames] + + return cached_filenames, sharded_metadata + + +def _check_legacy_sharding_variant_format(folder: str = None, filenames: List[str] = None, variant: str = None): + if filenames and folder: + raise ValueError("Both `filenames` and `folder` cannot be provided.") + if not filenames: + filenames = [] + for _, _, files in os.walk(folder): + for file in files: + filenames.append(os.path.basename(file)) + transformers_index_format = r"\d{5}-of-\d{5}" + variant_file_re = re.compile(rf".*-{transformers_index_format}\.{variant}\.[a-z]+$") + return any(variant_file_re.match(f) is not None for f in filenames) + + +class PushToHubMixin: + """ + A Mixin to push a model, scheduler, or pipeline to the Hugging Face Hub. + """ + + def _upload_folder( + self, + working_dir: Union[str, os.PathLike], + repo_id: str, + token: Optional[str] = None, + commit_message: Optional[str] = None, + create_pr: bool = False, + ): + """ + Uploads all files in `working_dir` to `repo_id`. + """ + if commit_message is None: + if "Model" in self.__class__.__name__: + commit_message = "Upload model" + elif "Scheduler" in self.__class__.__name__: + commit_message = "Upload scheduler" + else: + commit_message = f"Upload {self.__class__.__name__}" + + logger.info(f"Uploading the files of {working_dir} to {repo_id}.") + return upload_folder( + repo_id=repo_id, folder_path=working_dir, token=token, commit_message=commit_message, create_pr=create_pr + ) + + def push_to_hub( + self, + repo_id: str, + commit_message: Optional[str] = None, + private: Optional[bool] = None, + token: Optional[str] = None, + create_pr: bool = False, + safe_serialization: bool = True, + variant: Optional[str] = None, + ) -> str: + """ + Upload model, scheduler, or pipeline files to the 🤗 Hugging Face Hub. + + Parameters: + repo_id (`str`): + The name of the repository you want to push your model, scheduler, or pipeline files to. It should + contain your organization name when pushing to an organization. `repo_id` can also be a path to a local + directory. + commit_message (`str`, *optional*): + Message to commit while pushing. Default to `"Upload {object}"`. + private (`bool`, *optional*): + Whether to make the repo private. If `None` (default), the repo will be public unless the + organization's default is private. This value is ignored if the repo already exists. + token (`str`, *optional*): + The token to use as HTTP bearer authorization for remote files. The token generated when running + `huggingface-cli login` (stored in `~/.huggingface`). + create_pr (`bool`, *optional*, defaults to `False`): + Whether or not to create a PR with the uploaded files or directly commit. + safe_serialization (`bool`, *optional*, defaults to `True`): + Whether or not to convert the model weights to the `safetensors` format. + variant (`str`, *optional*): + If specified, weights are saved in the format `pytorch_model..bin`. + + Examples: + + ```python + from diffusers import UNet2DConditionModel + + unet = UNet2DConditionModel.from_pretrained("stabilityai/stable-diffusion-2", subfolder="unet") + + # Push the `unet` to your namespace with the name "my-finetuned-unet". + unet.push_to_hub("my-finetuned-unet") + + # Push the `unet` to an organization with the name "my-finetuned-unet". + unet.push_to_hub("your-org/my-finetuned-unet") + ``` + """ + repo_id = create_repo(repo_id, private=private, token=token, exist_ok=True).repo_id + + # Create a new empty model card and eventually tag it + model_card = load_or_create_model_card(repo_id, token=token) + model_card = populate_model_card(model_card) + + # Save all files. + save_kwargs = {"safe_serialization": safe_serialization} + if "Scheduler" not in self.__class__.__name__: + save_kwargs.update({"variant": variant}) + + with tempfile.TemporaryDirectory() as tmpdir: + self.save_pretrained(tmpdir, **save_kwargs) + + # Update model card if needed: + model_card.save(os.path.join(tmpdir, "README.md")) + + return self._upload_folder( + tmpdir, + repo_id, + token=token, + commit_message=commit_message, + create_pr=create_pr, + ) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/import_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/import_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..f7244e97b8784c3479d64726c081478695ca56a7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/import_utils.py @@ -0,0 +1,890 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Import utilities: Utilities related to imports and our lazy inits. +""" + +import importlib.util +import inspect +import operator as op +import os +import sys +from collections import OrderedDict, defaultdict +from itertools import chain +from types import ModuleType +from typing import Any, Tuple, Union + +from huggingface_hub.utils import is_jinja_available # noqa: F401 +from packaging.version import Version, parse + +from . import logging + + +# The package importlib_metadata is in a different place, depending on the python version. +if sys.version_info < (3, 8): + import importlib_metadata +else: + import importlib.metadata as importlib_metadata +try: + _package_map = importlib_metadata.packages_distributions() # load-once to avoid expensive calls +except Exception: + _package_map = None + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + +ENV_VARS_TRUE_VALUES = {"1", "ON", "YES", "TRUE"} +ENV_VARS_TRUE_AND_AUTO_VALUES = ENV_VARS_TRUE_VALUES.union({"AUTO"}) + +USE_TF = os.environ.get("USE_TF", "AUTO").upper() +USE_TORCH = os.environ.get("USE_TORCH", "AUTO").upper() +USE_JAX = os.environ.get("USE_FLAX", "AUTO").upper() +USE_SAFETENSORS = os.environ.get("USE_SAFETENSORS", "AUTO").upper() +DIFFUSERS_SLOW_IMPORT = os.environ.get("DIFFUSERS_SLOW_IMPORT", "FALSE").upper() +DIFFUSERS_SLOW_IMPORT = DIFFUSERS_SLOW_IMPORT in ENV_VARS_TRUE_VALUES + +STR_OPERATION_TO_FUNC = {">": op.gt, ">=": op.ge, "==": op.eq, "!=": op.ne, "<=": op.le, "<": op.lt} + +_is_google_colab = "google.colab" in sys.modules or any(k.startswith("COLAB_") for k in os.environ) + + +def _is_package_available(pkg_name: str, get_dist_name: bool = False) -> Tuple[bool, str]: + global _package_map + pkg_exists = importlib.util.find_spec(pkg_name) is not None + pkg_version = "N/A" + + if pkg_exists: + if _package_map is None: + _package_map = defaultdict(list) + try: + # Fallback for Python < 3.10 + for dist in importlib_metadata.distributions(): + _top_level_declared = (dist.read_text("top_level.txt") or "").split() + _infered_opt_names = { + f.parts[0] if len(f.parts) > 1 else inspect.getmodulename(f) for f in (dist.files or []) + } - {None} + _top_level_inferred = filter(lambda name: "." not in name, _infered_opt_names) + for pkg in _top_level_declared or _top_level_inferred: + _package_map[pkg].append(dist.metadata["Name"]) + except Exception as _: + pass + try: + if get_dist_name and pkg_name in _package_map and _package_map[pkg_name]: + if len(_package_map[pkg_name]) > 1: + logger.warning( + f"Multiple distributions found for package {pkg_name}. Picked distribution: {_package_map[pkg_name][0]}" + ) + pkg_name = _package_map[pkg_name][0] + pkg_version = importlib_metadata.version(pkg_name) + logger.debug(f"Successfully imported {pkg_name} version {pkg_version}") + except (ImportError, importlib_metadata.PackageNotFoundError): + pkg_exists = False + + return pkg_exists, pkg_version + + +if USE_TORCH in ENV_VARS_TRUE_AND_AUTO_VALUES and USE_TF not in ENV_VARS_TRUE_VALUES: + _torch_available, _torch_version = _is_package_available("torch") + +else: + logger.info("Disabling PyTorch because USE_TORCH is set") + _torch_available = False + +_jax_version = "N/A" +_flax_version = "N/A" +if USE_JAX in ENV_VARS_TRUE_AND_AUTO_VALUES: + _flax_available = importlib.util.find_spec("jax") is not None and importlib.util.find_spec("flax") is not None + if _flax_available: + try: + _jax_version = importlib_metadata.version("jax") + _flax_version = importlib_metadata.version("flax") + logger.info(f"JAX version {_jax_version}, Flax version {_flax_version} available.") + except importlib_metadata.PackageNotFoundError: + _flax_available = False +else: + _flax_available = False + +if USE_SAFETENSORS in ENV_VARS_TRUE_AND_AUTO_VALUES: + _safetensors_available, _safetensors_version = _is_package_available("safetensors") + +else: + logger.info("Disabling Safetensors because USE_TF is set") + _safetensors_available = False + +_onnxruntime_version = "N/A" +_onnx_available = importlib.util.find_spec("onnxruntime") is not None +if _onnx_available: + candidates = ( + "onnxruntime", + "onnxruntime-cann", + "onnxruntime-directml", + "ort_nightly_directml", + "onnxruntime-gpu", + "ort_nightly_gpu", + "onnxruntime-migraphx", + "onnxruntime-openvino", + "onnxruntime-qnn", + "onnxruntime-rocm", + "onnxruntime-training", + "onnxruntime-vitisai", + ) + _onnxruntime_version = None + # For the metadata, we have to look for both onnxruntime and onnxruntime-x + for pkg in candidates: + try: + _onnxruntime_version = importlib_metadata.version(pkg) + break + except importlib_metadata.PackageNotFoundError: + pass + _onnx_available = _onnxruntime_version is not None + if _onnx_available: + logger.debug(f"Successfully imported onnxruntime version {_onnxruntime_version}") + +# (sayakpaul): importlib.util.find_spec("opencv-python") returns None even when it's installed. +# _opencv_available = importlib.util.find_spec("opencv-python") is not None +try: + candidates = ( + "opencv-python", + "opencv-contrib-python", + "opencv-python-headless", + "opencv-contrib-python-headless", + ) + _opencv_version = None + for pkg in candidates: + try: + _opencv_version = importlib_metadata.version(pkg) + break + except importlib_metadata.PackageNotFoundError: + pass + _opencv_available = _opencv_version is not None + if _opencv_available: + logger.debug(f"Successfully imported cv2 version {_opencv_version}") +except importlib_metadata.PackageNotFoundError: + _opencv_available = False + +_bs4_available = importlib.util.find_spec("bs4") is not None +try: + # importlib metadata under different name + _bs4_version = importlib_metadata.version("beautifulsoup4") + logger.debug(f"Successfully imported ftfy version {_bs4_version}") +except importlib_metadata.PackageNotFoundError: + _bs4_available = False + +_invisible_watermark_available = importlib.util.find_spec("imwatermark") is not None +try: + _invisible_watermark_version = importlib_metadata.version("invisible-watermark") + logger.debug(f"Successfully imported invisible-watermark version {_invisible_watermark_version}") +except importlib_metadata.PackageNotFoundError: + _invisible_watermark_available = False + +_torch_xla_available, _torch_xla_version = _is_package_available("torch_xla") +_torch_npu_available, _torch_npu_version = _is_package_available("torch_npu") +_transformers_available, _transformers_version = _is_package_available("transformers") +_hf_hub_available, _hf_hub_version = _is_package_available("huggingface_hub") +_inflect_available, _inflect_version = _is_package_available("inflect") +_unidecode_available, _unidecode_version = _is_package_available("unidecode") +_k_diffusion_available, _k_diffusion_version = _is_package_available("k_diffusion") +_note_seq_available, _note_seq_version = _is_package_available("note_seq") +_wandb_available, _wandb_version = _is_package_available("wandb") +_tensorboard_available, _tensorboard_version = _is_package_available("tensorboard") +_compel_available, _compel_version = _is_package_available("compel") +_sentencepiece_available, _sentencepiece_version = _is_package_available("sentencepiece") +_torchsde_available, _torchsde_version = _is_package_available("torchsde") +_peft_available, _peft_version = _is_package_available("peft") +_torchvision_available, _torchvision_version = _is_package_available("torchvision") +_matplotlib_available, _matplotlib_version = _is_package_available("matplotlib") +_timm_available, _timm_version = _is_package_available("timm") +_bitsandbytes_available, _bitsandbytes_version = _is_package_available("bitsandbytes") +_imageio_available, _imageio_version = _is_package_available("imageio") +_ftfy_available, _ftfy_version = _is_package_available("ftfy") +_scipy_available, _scipy_version = _is_package_available("scipy") +_librosa_available, _librosa_version = _is_package_available("librosa") +_accelerate_available, _accelerate_version = _is_package_available("accelerate") +_xformers_available, _xformers_version = _is_package_available("xformers") +_gguf_available, _gguf_version = _is_package_available("gguf") +_torchao_available, _torchao_version = _is_package_available("torchao") +_bitsandbytes_available, _bitsandbytes_version = _is_package_available("bitsandbytes") +_optimum_quanto_available, _optimum_quanto_version = _is_package_available("optimum", get_dist_name=True) +_pytorch_retinaface_available, _pytorch_retinaface_version = _is_package_available("pytorch_retinaface") +_better_profanity_available, _better_profanity_version = _is_package_available("better_profanity") +_nltk_available, _nltk_version = _is_package_available("nltk") +_cosmos_guardrail_available, _cosmos_guardrail_version = _is_package_available("cosmos_guardrail") + + +def is_torch_available(): + return _torch_available + + +def is_torch_xla_available(): + return _torch_xla_available + + +def is_torch_npu_available(): + return _torch_npu_available + + +def is_flax_available(): + return _flax_available + + +def is_transformers_available(): + return _transformers_available + + +def is_inflect_available(): + return _inflect_available + + +def is_unidecode_available(): + return _unidecode_available + + +def is_onnx_available(): + return _onnx_available + + +def is_opencv_available(): + return _opencv_available + + +def is_scipy_available(): + return _scipy_available + + +def is_librosa_available(): + return _librosa_available + + +def is_xformers_available(): + return _xformers_available + + +def is_accelerate_available(): + return _accelerate_available + + +def is_k_diffusion_available(): + return _k_diffusion_available + + +def is_note_seq_available(): + return _note_seq_available + + +def is_wandb_available(): + return _wandb_available + + +def is_tensorboard_available(): + return _tensorboard_available + + +def is_compel_available(): + return _compel_available + + +def is_ftfy_available(): + return _ftfy_available + + +def is_bs4_available(): + return _bs4_available + + +def is_torchsde_available(): + return _torchsde_available + + +def is_invisible_watermark_available(): + return _invisible_watermark_available + + +def is_peft_available(): + return _peft_available + + +def is_torchvision_available(): + return _torchvision_available + + +def is_matplotlib_available(): + return _matplotlib_available + + +def is_safetensors_available(): + return _safetensors_available + + +def is_bitsandbytes_available(): + return _bitsandbytes_available + + +def is_google_colab(): + return _is_google_colab + + +def is_sentencepiece_available(): + return _sentencepiece_available + + +def is_imageio_available(): + return _imageio_available + + +def is_gguf_available(): + return _gguf_available + + +def is_torchao_available(): + return _torchao_available + + +def is_optimum_quanto_available(): + return _optimum_quanto_available + + +def is_timm_available(): + return _timm_available + + +def is_pytorch_retinaface_available(): + return _pytorch_retinaface_available + + +def is_better_profanity_available(): + return _better_profanity_available + + +def is_nltk_available(): + return _nltk_available + + +def is_cosmos_guardrail_available(): + return _cosmos_guardrail_available + + +def is_hpu_available(): + return all(importlib.util.find_spec(lib) for lib in ("habana_frameworks", "habana_frameworks.torch")) + + +# docstyle-ignore +FLAX_IMPORT_ERROR = """ +{0} requires the FLAX library but it was not found in your environment. Checkout the instructions on the +installation page: https://github.com/google/flax and follow the ones that match your environment. +""" + +# docstyle-ignore +INFLECT_IMPORT_ERROR = """ +{0} requires the inflect library but it was not found in your environment. You can install it with pip: `pip install +inflect` +""" + +# docstyle-ignore +PYTORCH_IMPORT_ERROR = """ +{0} requires the PyTorch library but it was not found in your environment. Checkout the instructions on the +installation page: https://pytorch.org/get-started/locally/ and follow the ones that match your environment. +""" + +# docstyle-ignore +ONNX_IMPORT_ERROR = """ +{0} requires the onnxruntime library but it was not found in your environment. You can install it with pip: `pip +install onnxruntime` +""" + +# docstyle-ignore +OPENCV_IMPORT_ERROR = """ +{0} requires the OpenCV library but it was not found in your environment. You can install it with pip: `pip +install opencv-python` +""" + +# docstyle-ignore +SCIPY_IMPORT_ERROR = """ +{0} requires the scipy library but it was not found in your environment. You can install it with pip: `pip install +scipy` +""" + +# docstyle-ignore +LIBROSA_IMPORT_ERROR = """ +{0} requires the librosa library but it was not found in your environment. Checkout the instructions on the +installation page: https://librosa.org/doc/latest/install.html and follow the ones that match your environment. +""" + +# docstyle-ignore +TRANSFORMERS_IMPORT_ERROR = """ +{0} requires the transformers library but it was not found in your environment. You can install it with pip: `pip +install transformers` +""" + +# docstyle-ignore +UNIDECODE_IMPORT_ERROR = """ +{0} requires the unidecode library but it was not found in your environment. You can install it with pip: `pip install +Unidecode` +""" + +# docstyle-ignore +K_DIFFUSION_IMPORT_ERROR = """ +{0} requires the k-diffusion library but it was not found in your environment. You can install it with pip: `pip +install k-diffusion` +""" + +# docstyle-ignore +NOTE_SEQ_IMPORT_ERROR = """ +{0} requires the note-seq library but it was not found in your environment. You can install it with pip: `pip +install note-seq` +""" + +# docstyle-ignore +WANDB_IMPORT_ERROR = """ +{0} requires the wandb library but it was not found in your environment. You can install it with pip: `pip +install wandb` +""" + +# docstyle-ignore +TENSORBOARD_IMPORT_ERROR = """ +{0} requires the tensorboard library but it was not found in your environment. You can install it with pip: `pip +install tensorboard` +""" + + +# docstyle-ignore +COMPEL_IMPORT_ERROR = """ +{0} requires the compel library but it was not found in your environment. You can install it with pip: `pip install compel` +""" + +# docstyle-ignore +BS4_IMPORT_ERROR = """ +{0} requires the Beautiful Soup library but it was not found in your environment. You can install it with pip: +`pip install beautifulsoup4`. Please note that you may need to restart your runtime after installation. +""" + +# docstyle-ignore +FTFY_IMPORT_ERROR = """ +{0} requires the ftfy library but it was not found in your environment. Checkout the instructions on the +installation section: https://github.com/rspeer/python-ftfy/tree/master#installing and follow the ones +that match your environment. Please note that you may need to restart your runtime after installation. +""" + +# docstyle-ignore +TORCHSDE_IMPORT_ERROR = """ +{0} requires the torchsde library but it was not found in your environment. You can install it with pip: `pip install torchsde` +""" + +# docstyle-ignore +INVISIBLE_WATERMARK_IMPORT_ERROR = """ +{0} requires the invisible-watermark library but it was not found in your environment. You can install it with pip: `pip install invisible-watermark>=0.2.0` +""" + +# docstyle-ignore +PEFT_IMPORT_ERROR = """ +{0} requires the peft library but it was not found in your environment. You can install it with pip: `pip install peft` +""" + +# docstyle-ignore +SAFETENSORS_IMPORT_ERROR = """ +{0} requires the safetensors library but it was not found in your environment. You can install it with pip: `pip install safetensors` +""" + +# docstyle-ignore +SENTENCEPIECE_IMPORT_ERROR = """ +{0} requires the sentencepiece library but it was not found in your environment. You can install it with pip: `pip install sentencepiece` +""" + + +# docstyle-ignore +BITSANDBYTES_IMPORT_ERROR = """ +{0} requires the bitsandbytes library but it was not found in your environment. You can install it with pip: `pip install bitsandbytes` +""" + +# docstyle-ignore +IMAGEIO_IMPORT_ERROR = """ +{0} requires the imageio library and ffmpeg but it was not found in your environment. You can install it with pip: `pip install imageio imageio-ffmpeg` +""" + +# docstyle-ignore +GGUF_IMPORT_ERROR = """ +{0} requires the gguf library but it was not found in your environment. You can install it with pip: `pip install gguf` +""" + +TORCHAO_IMPORT_ERROR = """ +{0} requires the torchao library but it was not found in your environment. You can install it with pip: `pip install +torchao` +""" + +QUANTO_IMPORT_ERROR = """ +{0} requires the optimum-quanto library but it was not found in your environment. You can install it with pip: `pip +install optimum-quanto` +""" + +# docstyle-ignore +PYTORCH_RETINAFACE_IMPORT_ERROR = """ +{0} requires the pytorch_retinaface library but it was not found in your environment. You can install it with pip: `pip install pytorch_retinaface` +""" + +# docstyle-ignore +BETTER_PROFANITY_IMPORT_ERROR = """ +{0} requires the better_profanity library but it was not found in your environment. You can install it with pip: `pip install better_profanity` +""" + +# docstyle-ignore +NLTK_IMPORT_ERROR = """ +{0} requires the nltk library but it was not found in your environment. You can install it with pip: `pip install nltk` +""" + + +BACKENDS_MAPPING = OrderedDict( + [ + ("bs4", (is_bs4_available, BS4_IMPORT_ERROR)), + ("flax", (is_flax_available, FLAX_IMPORT_ERROR)), + ("inflect", (is_inflect_available, INFLECT_IMPORT_ERROR)), + ("onnx", (is_onnx_available, ONNX_IMPORT_ERROR)), + ("opencv", (is_opencv_available, OPENCV_IMPORT_ERROR)), + ("scipy", (is_scipy_available, SCIPY_IMPORT_ERROR)), + ("torch", (is_torch_available, PYTORCH_IMPORT_ERROR)), + ("transformers", (is_transformers_available, TRANSFORMERS_IMPORT_ERROR)), + ("unidecode", (is_unidecode_available, UNIDECODE_IMPORT_ERROR)), + ("librosa", (is_librosa_available, LIBROSA_IMPORT_ERROR)), + ("k_diffusion", (is_k_diffusion_available, K_DIFFUSION_IMPORT_ERROR)), + ("note_seq", (is_note_seq_available, NOTE_SEQ_IMPORT_ERROR)), + ("wandb", (is_wandb_available, WANDB_IMPORT_ERROR)), + ("tensorboard", (is_tensorboard_available, TENSORBOARD_IMPORT_ERROR)), + ("compel", (is_compel_available, COMPEL_IMPORT_ERROR)), + ("ftfy", (is_ftfy_available, FTFY_IMPORT_ERROR)), + ("torchsde", (is_torchsde_available, TORCHSDE_IMPORT_ERROR)), + ("invisible_watermark", (is_invisible_watermark_available, INVISIBLE_WATERMARK_IMPORT_ERROR)), + ("peft", (is_peft_available, PEFT_IMPORT_ERROR)), + ("safetensors", (is_safetensors_available, SAFETENSORS_IMPORT_ERROR)), + ("bitsandbytes", (is_bitsandbytes_available, BITSANDBYTES_IMPORT_ERROR)), + ("sentencepiece", (is_sentencepiece_available, SENTENCEPIECE_IMPORT_ERROR)), + ("imageio", (is_imageio_available, IMAGEIO_IMPORT_ERROR)), + ("gguf", (is_gguf_available, GGUF_IMPORT_ERROR)), + ("torchao", (is_torchao_available, TORCHAO_IMPORT_ERROR)), + ("quanto", (is_optimum_quanto_available, QUANTO_IMPORT_ERROR)), + ("pytorch_retinaface", (is_pytorch_retinaface_available, PYTORCH_RETINAFACE_IMPORT_ERROR)), + ("better_profanity", (is_better_profanity_available, BETTER_PROFANITY_IMPORT_ERROR)), + ("nltk", (is_nltk_available, NLTK_IMPORT_ERROR)), + ] +) + + +def requires_backends(obj, backends): + if not isinstance(backends, (list, tuple)): + backends = [backends] + + name = obj.__name__ if hasattr(obj, "__name__") else obj.__class__.__name__ + checks = (BACKENDS_MAPPING[backend] for backend in backends) + failed = [msg.format(name) for available, msg in checks if not available()] + if failed: + raise ImportError("".join(failed)) + + if name in [ + "VersatileDiffusionTextToImagePipeline", + "VersatileDiffusionPipeline", + "VersatileDiffusionDualGuidedPipeline", + "StableDiffusionImageVariationPipeline", + "UnCLIPPipeline", + ] and is_transformers_version("<", "4.25.0"): + raise ImportError( + f"You need to install `transformers>=4.25` in order to use {name}: \n```\n pip install" + " --upgrade transformers \n```" + ) + + if name in ["StableDiffusionDepth2ImgPipeline", "StableDiffusionPix2PixZeroPipeline"] and is_transformers_version( + "<", "4.26.0" + ): + raise ImportError( + f"You need to install `transformers>=4.26` in order to use {name}: \n```\n pip install" + " --upgrade transformers \n```" + ) + + +class DummyObject(type): + """ + Metaclass for the dummy objects. Any class inheriting from it will return the ImportError generated by + `requires_backend` each time a user tries to access any method of that class. + """ + + def __getattr__(cls, key): + if key.startswith("_") and key not in ["_load_connected_pipes", "_is_onnx"]: + return super().__getattr__(cls, key) + requires_backends(cls, cls._backends) + + +# This function was copied from: https://github.com/huggingface/accelerate/blob/874c4967d94badd24f893064cc3bef45f57cadf7/src/accelerate/utils/versions.py#L319 +def compare_versions(library_or_version: Union[str, Version], operation: str, requirement_version: str): + """ + Compares a library version to some requirement using a given operation. + + Args: + library_or_version (`str` or `packaging.version.Version`): + A library name or a version to check. + operation (`str`): + A string representation of an operator, such as `">"` or `"<="`. + requirement_version (`str`): + The version to compare the library version against + """ + if operation not in STR_OPERATION_TO_FUNC.keys(): + raise ValueError(f"`operation` must be one of {list(STR_OPERATION_TO_FUNC.keys())}, received {operation}") + operation = STR_OPERATION_TO_FUNC[operation] + if isinstance(library_or_version, str): + library_or_version = parse(importlib_metadata.version(library_or_version)) + return operation(library_or_version, parse(requirement_version)) + + +# This function was copied from: https://github.com/huggingface/accelerate/blob/874c4967d94badd24f893064cc3bef45f57cadf7/src/accelerate/utils/versions.py#L338 +def is_torch_version(operation: str, version: str): + """ + Compares the current PyTorch version to a given reference with an operation. + + Args: + operation (`str`): + A string representation of an operator, such as `">"` or `"<="` + version (`str`): + A string version of PyTorch + """ + return compare_versions(parse(_torch_version), operation, version) + + +def is_torch_xla_version(operation: str, version: str): + """ + Compares the current torch_xla version to a given reference with an operation. + + Args: + operation (`str`): + A string representation of an operator, such as `">"` or `"<="` + version (`str`): + A string version of torch_xla + """ + if not is_torch_xla_available: + return False + return compare_versions(parse(_torch_xla_version), operation, version) + + +def is_transformers_version(operation: str, version: str): + """ + Compares the current Transformers version to a given reference with an operation. + + Args: + operation (`str`): + A string representation of an operator, such as `">"` or `"<="` + version (`str`): + A version string + """ + if not _transformers_available: + return False + return compare_versions(parse(_transformers_version), operation, version) + + +def is_hf_hub_version(operation: str, version: str): + """ + Compares the current Hugging Face Hub version to a given reference with an operation. + + Args: + operation (`str`): + A string representation of an operator, such as `">"` or `"<="` + version (`str`): + A version string + """ + if not _hf_hub_available: + return False + return compare_versions(parse(_hf_hub_version), operation, version) + + +def is_accelerate_version(operation: str, version: str): + """ + Compares the current Accelerate version to a given reference with an operation. + + Args: + operation (`str`): + A string representation of an operator, such as `">"` or `"<="` + version (`str`): + A version string + """ + if not _accelerate_available: + return False + return compare_versions(parse(_accelerate_version), operation, version) + + +def is_peft_version(operation: str, version: str): + """ + Compares the current PEFT version to a given reference with an operation. + + Args: + operation (`str`): + A string representation of an operator, such as `">"` or `"<="` + version (`str`): + A version string + """ + if not _peft_available: + return False + return compare_versions(parse(_peft_version), operation, version) + + +def is_bitsandbytes_version(operation: str, version: str): + """ + Args: + Compares the current bitsandbytes version to a given reference with an operation. + operation (`str`): + A string representation of an operator, such as `">"` or `"<="` + version (`str`): + A version string + """ + if not _bitsandbytes_available: + return False + return compare_versions(parse(_bitsandbytes_version), operation, version) + + +def is_gguf_version(operation: str, version: str): + """ + Compares the current Accelerate version to a given reference with an operation. + + Args: + operation (`str`): + A string representation of an operator, such as `">"` or `"<="` + version (`str`): + A version string + """ + if not _gguf_available: + return False + return compare_versions(parse(_gguf_version), operation, version) + + +def is_torchao_version(operation: str, version: str): + """ + Compares the current torchao version to a given reference with an operation. + + Args: + operation (`str`): + A string representation of an operator, such as `">"` or `"<="` + version (`str`): + A version string + """ + if not _torchao_available: + return False + return compare_versions(parse(_torchao_version), operation, version) + + +def is_k_diffusion_version(operation: str, version: str): + """ + Compares the current k-diffusion version to a given reference with an operation. + + Args: + operation (`str`): + A string representation of an operator, such as `">"` or `"<="` + version (`str`): + A version string + """ + if not _k_diffusion_available: + return False + return compare_versions(parse(_k_diffusion_version), operation, version) + + +def is_optimum_quanto_version(operation: str, version: str): + """ + Compares the current Accelerate version to a given reference with an operation. + + Args: + operation (`str`): + A string representation of an operator, such as `">"` or `"<="` + version (`str`): + A version string + """ + if not _optimum_quanto_available: + return False + return compare_versions(parse(_optimum_quanto_version), operation, version) + + +def get_objects_from_module(module): + """ + Returns a dict of object names and values in a module, while skipping private/internal objects + + Args: + module (ModuleType): + Module to extract the objects from. + + Returns: + dict: Dictionary of object names and corresponding values + """ + + objects = {} + for name in dir(module): + if name.startswith("_"): + continue + objects[name] = getattr(module, name) + + return objects + + +class OptionalDependencyNotAvailable(BaseException): + """ + An error indicating that an optional dependency of Diffusers was not found in the environment. + """ + + +class _LazyModule(ModuleType): + """ + Module class that surfaces all objects but only performs associated imports when the objects are requested. + """ + + # Very heavily inspired by optuna.integration._IntegrationModule + # https://github.com/optuna/optuna/blob/master/optuna/integration/__init__.py + def __init__(self, name, module_file, import_structure, module_spec=None, extra_objects=None): + super().__init__(name) + self._modules = set(import_structure.keys()) + self._class_to_module = {} + for key, values in import_structure.items(): + for value in values: + self._class_to_module[value] = key + # Needed for autocompletion in an IDE + self.__all__ = list(import_structure.keys()) + list(chain(*import_structure.values())) + self.__file__ = module_file + self.__spec__ = module_spec + self.__path__ = [os.path.dirname(module_file)] + self._objects = {} if extra_objects is None else extra_objects + self._name = name + self._import_structure = import_structure + + # Needed for autocompletion in an IDE + def __dir__(self): + result = super().__dir__() + # The elements of self.__all__ that are submodules may or may not be in the dir already, depending on whether + # they have been accessed or not. So we only add the elements of self.__all__ that are not already in the dir. + for attr in self.__all__: + if attr not in result: + result.append(attr) + return result + + def __getattr__(self, name: str) -> Any: + if name in self._objects: + return self._objects[name] + if name in self._modules: + value = self._get_module(name) + elif name in self._class_to_module.keys(): + module = self._get_module(self._class_to_module[name]) + value = getattr(module, name) + else: + raise AttributeError(f"module {self.__name__} has no attribute {name}") + + setattr(self, name, value) + return value + + def _get_module(self, module_name: str): + try: + return importlib.import_module("." + module_name, self.__name__) + except Exception as e: + raise RuntimeError( + f"Failed to import {self.__name__}.{module_name} because of the following error (look up to see its" + f" traceback):\n{e}" + ) from e + + def __reduce__(self): + return (self.__class__, (self._name, self.__file__, self._import_structure)) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/loading_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/loading_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..dd23ae73c86175a5736af5f98d27bcd3c7a63859 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/loading_utils.py @@ -0,0 +1,163 @@ +import os +import tempfile +from typing import Any, Callable, List, Optional, Tuple, Union +from urllib.parse import unquote, urlparse + +import PIL.Image +import PIL.ImageOps +import requests + +from .constants import DIFFUSERS_REQUEST_TIMEOUT +from .import_utils import BACKENDS_MAPPING, is_imageio_available + + +def load_image( + image: Union[str, PIL.Image.Image], convert_method: Optional[Callable[[PIL.Image.Image], PIL.Image.Image]] = None +) -> PIL.Image.Image: + """ + Loads `image` to a PIL Image. + + Args: + image (`str` or `PIL.Image.Image`): + The image to convert to the PIL Image format. + convert_method (Callable[[PIL.Image.Image], PIL.Image.Image], *optional*): + A conversion method to apply to the image after loading it. When set to `None` the image will be converted + "RGB". + + Returns: + `PIL.Image.Image`: + A PIL Image. + """ + if isinstance(image, str): + if image.startswith("http://") or image.startswith("https://"): + image = PIL.Image.open(requests.get(image, stream=True, timeout=DIFFUSERS_REQUEST_TIMEOUT).raw) + elif os.path.isfile(image): + image = PIL.Image.open(image) + else: + raise ValueError( + f"Incorrect path or URL. URLs must start with `http://` or `https://`, and {image} is not a valid path." + ) + elif isinstance(image, PIL.Image.Image): + image = image + else: + raise ValueError( + "Incorrect format used for the image. Should be a URL linking to an image, a local path, or a PIL image." + ) + + image = PIL.ImageOps.exif_transpose(image) + + if convert_method is not None: + image = convert_method(image) + else: + image = image.convert("RGB") + + return image + + +def load_video( + video: str, + convert_method: Optional[Callable[[List[PIL.Image.Image]], List[PIL.Image.Image]]] = None, +) -> List[PIL.Image.Image]: + """ + Loads `video` to a list of PIL Image. + + Args: + video (`str`): + A URL or Path to a video to convert to a list of PIL Image format. + convert_method (Callable[[List[PIL.Image.Image]], List[PIL.Image.Image]], *optional*): + A conversion method to apply to the video after loading it. When set to `None` the images will be converted + to "RGB". + + Returns: + `List[PIL.Image.Image]`: + The video as a list of PIL images. + """ + is_url = video.startswith("http://") or video.startswith("https://") + is_file = os.path.isfile(video) + was_tempfile_created = False + + if not (is_url or is_file): + raise ValueError( + f"Incorrect path or URL. URLs must start with `http://` or `https://`, and {video} is not a valid path." + ) + + if is_url: + response = requests.get(video, stream=True) + if response.status_code != 200: + raise ValueError(f"Failed to download video. Status code: {response.status_code}") + + parsed_url = urlparse(video) + file_name = os.path.basename(unquote(parsed_url.path)) + + suffix = os.path.splitext(file_name)[1] or ".mp4" + video_path = tempfile.NamedTemporaryFile(suffix=suffix, delete=False).name + + was_tempfile_created = True + + video_data = response.iter_content(chunk_size=8192) + with open(video_path, "wb") as f: + for chunk in video_data: + f.write(chunk) + + video = video_path + + pil_images = [] + if video.endswith(".gif"): + gif = PIL.Image.open(video) + try: + while True: + pil_images.append(gif.copy()) + gif.seek(gif.tell() + 1) + except EOFError: + pass + + else: + if is_imageio_available(): + import imageio + else: + raise ImportError(BACKENDS_MAPPING["imageio"][1].format("load_video")) + + try: + imageio.plugins.ffmpeg.get_exe() + except AttributeError: + raise AttributeError( + "`Unable to find an ffmpeg installation on your machine. Please install via `pip install imageio-ffmpeg" + ) + + with imageio.get_reader(video) as reader: + # Read all frames + for frame in reader: + pil_images.append(PIL.Image.fromarray(frame)) + + if was_tempfile_created: + os.remove(video_path) + + if convert_method is not None: + pil_images = convert_method(pil_images) + + return pil_images + + +# Taken from `transformers`. +def get_module_from_name(module, tensor_name: str) -> Tuple[Any, str]: + if "." in tensor_name: + splits = tensor_name.split(".") + for split in splits[:-1]: + new_module = getattr(module, split) + if new_module is None: + raise ValueError(f"{module} has no attribute {split}.") + module = new_module + tensor_name = splits[-1] + return module, tensor_name + + +def get_submodule_by_name(root_module, module_path: str): + current = root_module + parts = module_path.split(".") + for part in parts: + if part.isdigit(): + idx = int(part) + current = current[idx] # e.g., for nn.ModuleList or nn.Sequential + else: + current = getattr(current, part) + return current diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/logging.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/logging.py new file mode 100644 index 0000000000000000000000000000000000000000..b96e0e222cb1e24d3505a36181b58a2460fe89da --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/logging.py @@ -0,0 +1,340 @@ +# coding=utf-8 +# Copyright 2024 Optuna, Hugging Face +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +"""Logging utilities.""" + +import logging +import os +import sys +import threading +from logging import ( + CRITICAL, # NOQA + DEBUG, # NOQA + ERROR, # NOQA + FATAL, # NOQA + INFO, # NOQA + NOTSET, # NOQA + WARN, # NOQA + WARNING, # NOQA +) +from typing import Dict, Optional + +from tqdm import auto as tqdm_lib + + +_lock = threading.Lock() +_default_handler: Optional[logging.Handler] = None + +log_levels = { + "debug": logging.DEBUG, + "info": logging.INFO, + "warning": logging.WARNING, + "error": logging.ERROR, + "critical": logging.CRITICAL, +} + +_default_log_level = logging.WARNING + +_tqdm_active = True + + +def _get_default_logging_level() -> int: + """ + If DIFFUSERS_VERBOSITY env var is set to one of the valid choices return that as the new default level. If it is + not - fall back to `_default_log_level` + """ + env_level_str = os.getenv("DIFFUSERS_VERBOSITY", None) + if env_level_str: + if env_level_str in log_levels: + return log_levels[env_level_str] + else: + logging.getLogger().warning( + f"Unknown option DIFFUSERS_VERBOSITY={env_level_str}, has to be one of: {', '.join(log_levels.keys())}" + ) + return _default_log_level + + +def _get_library_name() -> str: + return __name__.split(".")[0] + + +def _get_library_root_logger() -> logging.Logger: + return logging.getLogger(_get_library_name()) + + +def _configure_library_root_logger() -> None: + global _default_handler + + with _lock: + if _default_handler: + # This library has already configured the library root logger. + return + _default_handler = logging.StreamHandler() # Set sys.stderr as stream. + + if sys.stderr: # only if sys.stderr exists, e.g. when not using pythonw in windows + _default_handler.flush = sys.stderr.flush + + # Apply our default configuration to the library root logger. + library_root_logger = _get_library_root_logger() + library_root_logger.addHandler(_default_handler) + library_root_logger.setLevel(_get_default_logging_level()) + library_root_logger.propagate = False + + +def _reset_library_root_logger() -> None: + global _default_handler + + with _lock: + if not _default_handler: + return + + library_root_logger = _get_library_root_logger() + library_root_logger.removeHandler(_default_handler) + library_root_logger.setLevel(logging.NOTSET) + _default_handler = None + + +def get_log_levels_dict() -> Dict[str, int]: + return log_levels + + +def get_logger(name: Optional[str] = None) -> logging.Logger: + """ + Return a logger with the specified name. + + This function is not supposed to be directly accessed unless you are writing a custom diffusers module. + """ + + if name is None: + name = _get_library_name() + + _configure_library_root_logger() + return logging.getLogger(name) + + +def get_verbosity() -> int: + """ + Return the current level for the 🤗 Diffusers' root logger as an `int`. + + Returns: + `int`: + Logging level integers which can be one of: + + - `50`: `diffusers.logging.CRITICAL` or `diffusers.logging.FATAL` + - `40`: `diffusers.logging.ERROR` + - `30`: `diffusers.logging.WARNING` or `diffusers.logging.WARN` + - `20`: `diffusers.logging.INFO` + - `10`: `diffusers.logging.DEBUG` + + """ + + _configure_library_root_logger() + return _get_library_root_logger().getEffectiveLevel() + + +def set_verbosity(verbosity: int) -> None: + """ + Set the verbosity level for the 🤗 Diffusers' root logger. + + Args: + verbosity (`int`): + Logging level which can be one of: + + - `diffusers.logging.CRITICAL` or `diffusers.logging.FATAL` + - `diffusers.logging.ERROR` + - `diffusers.logging.WARNING` or `diffusers.logging.WARN` + - `diffusers.logging.INFO` + - `diffusers.logging.DEBUG` + """ + + _configure_library_root_logger() + _get_library_root_logger().setLevel(verbosity) + + +def set_verbosity_info() -> None: + """Set the verbosity to the `INFO` level.""" + return set_verbosity(INFO) + + +def set_verbosity_warning() -> None: + """Set the verbosity to the `WARNING` level.""" + return set_verbosity(WARNING) + + +def set_verbosity_debug() -> None: + """Set the verbosity to the `DEBUG` level.""" + return set_verbosity(DEBUG) + + +def set_verbosity_error() -> None: + """Set the verbosity to the `ERROR` level.""" + return set_verbosity(ERROR) + + +def disable_default_handler() -> None: + """Disable the default handler of the 🤗 Diffusers' root logger.""" + + _configure_library_root_logger() + + assert _default_handler is not None + _get_library_root_logger().removeHandler(_default_handler) + + +def enable_default_handler() -> None: + """Enable the default handler of the 🤗 Diffusers' root logger.""" + + _configure_library_root_logger() + + assert _default_handler is not None + _get_library_root_logger().addHandler(_default_handler) + + +def add_handler(handler: logging.Handler) -> None: + """adds a handler to the HuggingFace Diffusers' root logger.""" + + _configure_library_root_logger() + + assert handler is not None + _get_library_root_logger().addHandler(handler) + + +def remove_handler(handler: logging.Handler) -> None: + """removes given handler from the HuggingFace Diffusers' root logger.""" + + _configure_library_root_logger() + + assert handler is not None and handler in _get_library_root_logger().handlers + _get_library_root_logger().removeHandler(handler) + + +def disable_propagation() -> None: + """ + Disable propagation of the library log outputs. Note that log propagation is disabled by default. + """ + + _configure_library_root_logger() + _get_library_root_logger().propagate = False + + +def enable_propagation() -> None: + """ + Enable propagation of the library log outputs. Please disable the HuggingFace Diffusers' default handler to prevent + double logging if the root logger has been configured. + """ + + _configure_library_root_logger() + _get_library_root_logger().propagate = True + + +def enable_explicit_format() -> None: + """ + Enable explicit formatting for every 🤗 Diffusers' logger. The explicit formatter is as follows: + ``` + [LEVELNAME|FILENAME|LINE NUMBER] TIME >> MESSAGE + ``` + All handlers currently bound to the root logger are affected by this method. + """ + handlers = _get_library_root_logger().handlers + + for handler in handlers: + formatter = logging.Formatter("[%(levelname)s|%(filename)s:%(lineno)s] %(asctime)s >> %(message)s") + handler.setFormatter(formatter) + + +def reset_format() -> None: + """ + Resets the formatting for 🤗 Diffusers' loggers. + + All handlers currently bound to the root logger are affected by this method. + """ + handlers = _get_library_root_logger().handlers + + for handler in handlers: + handler.setFormatter(None) + + +def warning_advice(self, *args, **kwargs) -> None: + """ + This method is identical to `logger.warning()`, but if env var DIFFUSERS_NO_ADVISORY_WARNINGS=1 is set, this + warning will not be printed + """ + no_advisory_warnings = os.getenv("DIFFUSERS_NO_ADVISORY_WARNINGS", False) + if no_advisory_warnings: + return + self.warning(*args, **kwargs) + + +logging.Logger.warning_advice = warning_advice + + +class EmptyTqdm: + """Dummy tqdm which doesn't do anything.""" + + def __init__(self, *args, **kwargs): # pylint: disable=unused-argument + self._iterator = args[0] if args else None + + def __iter__(self): + return iter(self._iterator) + + def __getattr__(self, _): + """Return empty function.""" + + def empty_fn(*args, **kwargs): # pylint: disable=unused-argument + return + + return empty_fn + + def __enter__(self): + return self + + def __exit__(self, type_, value, traceback): + return + + +class _tqdm_cls: + def __call__(self, *args, **kwargs): + if _tqdm_active: + return tqdm_lib.tqdm(*args, **kwargs) + else: + return EmptyTqdm(*args, **kwargs) + + def set_lock(self, *args, **kwargs): + self._lock = None + if _tqdm_active: + return tqdm_lib.tqdm.set_lock(*args, **kwargs) + + def get_lock(self): + if _tqdm_active: + return tqdm_lib.tqdm.get_lock() + + +tqdm = _tqdm_cls() + + +def is_progress_bar_enabled() -> bool: + """Return a boolean indicating whether tqdm progress bars are enabled.""" + global _tqdm_active + return bool(_tqdm_active) + + +def enable_progress_bar() -> None: + """Enable tqdm progress bar.""" + global _tqdm_active + _tqdm_active = True + + +def disable_progress_bar() -> None: + """Disable tqdm progress bar.""" + global _tqdm_active + _tqdm_active = False diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/model_card_template.md b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/model_card_template.md new file mode 100644 index 0000000000000000000000000000000000000000..f41b71e24e2081425d3049ae51b50036d5d28b6a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/model_card_template.md @@ -0,0 +1,24 @@ +--- +{{ card_data }} +--- + + + +{{ model_description }} + +## Intended uses & limitations + +#### How to use + +```python +# TODO: add an example code snippet for running this diffusion pipeline +``` + +#### Limitations and bias + +[TODO: provide examples of latent issues and potential remediations] + +## Training details + +[TODO: describe the data used to train the model] diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/outputs.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/outputs.py new file mode 100644 index 0000000000000000000000000000000000000000..c625746cf8a9907ea5afcf264b5d94305bc2033a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/outputs.py @@ -0,0 +1,138 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Generic utilities +""" + +from collections import OrderedDict +from dataclasses import fields, is_dataclass +from typing import Any, Tuple + +import numpy as np + +from .import_utils import is_torch_available, is_torch_version + + +def is_tensor(x) -> bool: + """ + Tests if `x` is a `torch.Tensor` or `np.ndarray`. + """ + if is_torch_available(): + import torch + + if isinstance(x, torch.Tensor): + return True + + return isinstance(x, np.ndarray) + + +class BaseOutput(OrderedDict): + """ + Base class for all model outputs as dataclass. Has a `__getitem__` that allows indexing by integer or slice (like a + tuple) or strings (like a dictionary) that will ignore the `None` attributes. Otherwise behaves like a regular + Python dictionary. + + + + You can't unpack a [`BaseOutput`] directly. Use the [`~utils.BaseOutput.to_tuple`] method to convert it to a tuple + first. + + + """ + + def __init_subclass__(cls) -> None: + """Register subclasses as pytree nodes. + + This is necessary to synchronize gradients when using `torch.nn.parallel.DistributedDataParallel` with + `static_graph=True` with modules that output `ModelOutput` subclasses. + """ + if is_torch_available(): + import torch.utils._pytree + + if is_torch_version("<", "2.2"): + torch.utils._pytree._register_pytree_node( + cls, + torch.utils._pytree._dict_flatten, + lambda values, context: cls(**torch.utils._pytree._dict_unflatten(values, context)), + ) + else: + torch.utils._pytree.register_pytree_node( + cls, + torch.utils._pytree._dict_flatten, + lambda values, context: cls(**torch.utils._pytree._dict_unflatten(values, context)), + serialized_type_name=f"{cls.__module__}.{cls.__name__}", + ) + + def __post_init__(self) -> None: + class_fields = fields(self) + + # Safety and consistency checks + if not len(class_fields): + raise ValueError(f"{self.__class__.__name__} has no fields.") + + first_field = getattr(self, class_fields[0].name) + other_fields_are_none = all(getattr(self, field.name) is None for field in class_fields[1:]) + + if other_fields_are_none and isinstance(first_field, dict): + for key, value in first_field.items(): + self[key] = value + else: + for field in class_fields: + v = getattr(self, field.name) + if v is not None: + self[field.name] = v + + def __delitem__(self, *args, **kwargs): + raise Exception(f"You cannot use ``__delitem__`` on a {self.__class__.__name__} instance.") + + def setdefault(self, *args, **kwargs): + raise Exception(f"You cannot use ``setdefault`` on a {self.__class__.__name__} instance.") + + def pop(self, *args, **kwargs): + raise Exception(f"You cannot use ``pop`` on a {self.__class__.__name__} instance.") + + def update(self, *args, **kwargs): + raise Exception(f"You cannot use ``update`` on a {self.__class__.__name__} instance.") + + def __getitem__(self, k: Any) -> Any: + if isinstance(k, str): + inner_dict = dict(self.items()) + return inner_dict[k] + else: + return self.to_tuple()[k] + + def __setattr__(self, name: Any, value: Any) -> None: + if name in self.keys() and value is not None: + # Don't call self.__setitem__ to avoid recursion errors + super().__setitem__(name, value) + super().__setattr__(name, value) + + def __setitem__(self, key, value): + # Will raise a KeyException if needed + super().__setitem__(key, value) + # Don't call self.__setattr__ to avoid recursion errors + super().__setattr__(key, value) + + def __reduce__(self): + if not is_dataclass(self): + return super().__reduce__() + callable, _args, *remaining = super().__reduce__() + args = tuple(getattr(self, field.name) for field in fields(self)) + return callable, args, *remaining + + def to_tuple(self) -> Tuple[Any, ...]: + """ + Convert self to a tuple containing all the attributes/keys that are not `None`. + """ + return tuple(self[k] for k in self.keys()) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/peft_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/peft_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..7d0a6faa7afb9b863a46043e713b1e61d9902574 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/peft_utils.py @@ -0,0 +1,290 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +PEFT utilities: Utilities related to peft library +""" + +import collections +import importlib +from typing import Optional + +from packaging import version + +from .import_utils import is_peft_available, is_torch_available + + +if is_torch_available(): + import torch + + +def recurse_remove_peft_layers(model): + r""" + Recursively replace all instances of `LoraLayer` with corresponding new layers in `model`. + """ + from peft.tuners.tuners_utils import BaseTunerLayer + + has_base_layer_pattern = False + for module in model.modules(): + if isinstance(module, BaseTunerLayer): + has_base_layer_pattern = hasattr(module, "base_layer") + break + + if has_base_layer_pattern: + from peft.utils import _get_submodules + + key_list = [key for key, _ in model.named_modules() if "lora" not in key] + for key in key_list: + try: + parent, target, target_name = _get_submodules(model, key) + except AttributeError: + continue + if hasattr(target, "base_layer"): + setattr(parent, target_name, target.get_base_layer()) + else: + # This is for backwards compatibility with PEFT <= 0.6.2. + # TODO can be removed once that PEFT version is no longer supported. + from peft.tuners.lora import LoraLayer + + for name, module in model.named_children(): + if len(list(module.children())) > 0: + ## compound module, go inside it + recurse_remove_peft_layers(module) + + module_replaced = False + + if isinstance(module, LoraLayer) and isinstance(module, torch.nn.Linear): + new_module = torch.nn.Linear( + module.in_features, + module.out_features, + bias=module.bias is not None, + ).to(module.weight.device) + new_module.weight = module.weight + if module.bias is not None: + new_module.bias = module.bias + + module_replaced = True + elif isinstance(module, LoraLayer) and isinstance(module, torch.nn.Conv2d): + new_module = torch.nn.Conv2d( + module.in_channels, + module.out_channels, + module.kernel_size, + module.stride, + module.padding, + module.dilation, + module.groups, + ).to(module.weight.device) + + new_module.weight = module.weight + if module.bias is not None: + new_module.bias = module.bias + + module_replaced = True + + if module_replaced: + setattr(model, name, new_module) + del module + + if torch.cuda.is_available(): + torch.cuda.empty_cache() + return model + + +def scale_lora_layers(model, weight): + """ + Adjust the weightage given to the LoRA layers of the model. + + Args: + model (`torch.nn.Module`): + The model to scale. + weight (`float`): + The weight to be given to the LoRA layers. + """ + from peft.tuners.tuners_utils import BaseTunerLayer + + if weight == 1.0: + return + + for module in model.modules(): + if isinstance(module, BaseTunerLayer): + module.scale_layer(weight) + + +def unscale_lora_layers(model, weight: Optional[float] = None): + """ + Removes the previously passed weight given to the LoRA layers of the model. + + Args: + model (`torch.nn.Module`): + The model to scale. + weight (`float`, *optional*): + The weight to be given to the LoRA layers. If no scale is passed the scale of the lora layer will be + re-initialized to the correct value. If 0.0 is passed, we will re-initialize the scale with the correct + value. + """ + from peft.tuners.tuners_utils import BaseTunerLayer + + if weight is None or weight == 1.0: + return + + for module in model.modules(): + if isinstance(module, BaseTunerLayer): + if weight != 0: + module.unscale_layer(weight) + else: + for adapter_name in module.active_adapters: + # if weight == 0 unscale should re-set the scale to the original value. + module.set_scale(adapter_name, 1.0) + + +def get_peft_kwargs(rank_dict, network_alpha_dict, peft_state_dict, is_unet=True): + rank_pattern = {} + alpha_pattern = {} + r = lora_alpha = list(rank_dict.values())[0] + + if len(set(rank_dict.values())) > 1: + # get the rank occurring the most number of times + r = collections.Counter(rank_dict.values()).most_common()[0][0] + + # for modules with rank different from the most occurring rank, add it to the `rank_pattern` + rank_pattern = dict(filter(lambda x: x[1] != r, rank_dict.items())) + rank_pattern = {k.split(".lora_B.")[0]: v for k, v in rank_pattern.items()} + + if network_alpha_dict is not None and len(network_alpha_dict) > 0: + if len(set(network_alpha_dict.values())) > 1: + # get the alpha occurring the most number of times + lora_alpha = collections.Counter(network_alpha_dict.values()).most_common()[0][0] + + # for modules with alpha different from the most occurring alpha, add it to the `alpha_pattern` + alpha_pattern = dict(filter(lambda x: x[1] != lora_alpha, network_alpha_dict.items())) + if is_unet: + alpha_pattern = { + ".".join(k.split(".lora_A.")[0].split(".")).replace(".alpha", ""): v + for k, v in alpha_pattern.items() + } + else: + alpha_pattern = {".".join(k.split(".down.")[0].split(".")[:-1]): v for k, v in alpha_pattern.items()} + else: + lora_alpha = set(network_alpha_dict.values()).pop() + + # layer names without the Diffusers specific + target_modules = list({name.split(".lora")[0] for name in peft_state_dict.keys()}) + use_dora = any("lora_magnitude_vector" in k for k in peft_state_dict) + # for now we know that the "bias" keys are only associated with `lora_B`. + lora_bias = any("lora_B" in k and k.endswith(".bias") for k in peft_state_dict) + + lora_config_kwargs = { + "r": r, + "lora_alpha": lora_alpha, + "rank_pattern": rank_pattern, + "alpha_pattern": alpha_pattern, + "target_modules": target_modules, + "use_dora": use_dora, + "lora_bias": lora_bias, + } + return lora_config_kwargs + + +def get_adapter_name(model): + from peft.tuners.tuners_utils import BaseTunerLayer + + for module in model.modules(): + if isinstance(module, BaseTunerLayer): + return f"default_{len(module.r)}" + return "default_0" + + +def set_adapter_layers(model, enabled=True): + from peft.tuners.tuners_utils import BaseTunerLayer + + for module in model.modules(): + if isinstance(module, BaseTunerLayer): + # The recent version of PEFT needs to call `enable_adapters` instead + if hasattr(module, "enable_adapters"): + module.enable_adapters(enabled=enabled) + else: + module.disable_adapters = not enabled + + +def delete_adapter_layers(model, adapter_name): + from peft.tuners.tuners_utils import BaseTunerLayer + + for module in model.modules(): + if isinstance(module, BaseTunerLayer): + if hasattr(module, "delete_adapter"): + module.delete_adapter(adapter_name) + else: + raise ValueError( + "The version of PEFT you are using is not compatible, please use a version that is greater than 0.6.1" + ) + + # For transformers integration - we need to pop the adapter from the config + if getattr(model, "_hf_peft_config_loaded", False) and hasattr(model, "peft_config"): + model.peft_config.pop(adapter_name, None) + # In case all adapters are deleted, we need to delete the config + # and make sure to set the flag to False + if len(model.peft_config) == 0: + del model.peft_config + model._hf_peft_config_loaded = None + + +def set_weights_and_activate_adapters(model, adapter_names, weights): + from peft.tuners.tuners_utils import BaseTunerLayer + + def get_module_weight(weight_for_adapter, module_name): + if not isinstance(weight_for_adapter, dict): + # If weight_for_adapter is a single number, always return it. + return weight_for_adapter + + for layer_name, weight_ in weight_for_adapter.items(): + if layer_name in module_name: + return weight_ + + parts = module_name.split(".") + # e.g. key = "down_blocks.1.attentions.0" + key = f"{parts[0]}.{parts[1]}.attentions.{parts[3]}" + block_weight = weight_for_adapter.get(key, 1.0) + + return block_weight + + for module_name, module in model.named_modules(): + if isinstance(module, BaseTunerLayer): + # For backward compatibility with previous PEFT versions, set multiple active adapters + if hasattr(module, "set_adapter"): + module.set_adapter(adapter_names) + else: + module.active_adapter = adapter_names + + # Set the scaling weight for each adapter for this module + for adapter_name, weight in zip(adapter_names, weights): + module.set_scale(adapter_name, get_module_weight(weight, module_name)) + + +def check_peft_version(min_version: str) -> None: + r""" + Checks if the version of PEFT is compatible. + + Args: + version (`str`): + The version of PEFT to check against. + """ + if not is_peft_available(): + raise ValueError("PEFT is not installed. Please install it with `pip install peft`") + + is_peft_version_compatible = version.parse(importlib.metadata.version("peft")) > version.parse(min_version) + + if not is_peft_version_compatible: + raise ValueError( + f"The version of PEFT you are using is not compatible, please use a version that is greater" + f" than {min_version}" + ) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/pil_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/pil_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..76678070b697c7d87fc3691d9bc5bb3bea83c5b1 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/pil_utils.py @@ -0,0 +1,67 @@ +from typing import List + +import PIL.Image +import PIL.ImageOps +from packaging import version +from PIL import Image + + +if version.parse(version.parse(PIL.__version__).base_version) >= version.parse("9.1.0"): + PIL_INTERPOLATION = { + "linear": PIL.Image.Resampling.BILINEAR, + "bilinear": PIL.Image.Resampling.BILINEAR, + "bicubic": PIL.Image.Resampling.BICUBIC, + "lanczos": PIL.Image.Resampling.LANCZOS, + "nearest": PIL.Image.Resampling.NEAREST, + } +else: + PIL_INTERPOLATION = { + "linear": PIL.Image.LINEAR, + "bilinear": PIL.Image.BILINEAR, + "bicubic": PIL.Image.BICUBIC, + "lanczos": PIL.Image.LANCZOS, + "nearest": PIL.Image.NEAREST, + } + + +def pt_to_pil(images): + """ + Convert a torch image to a PIL image. + """ + images = (images / 2 + 0.5).clamp(0, 1) + images = images.cpu().permute(0, 2, 3, 1).float().numpy() + images = numpy_to_pil(images) + return images + + +def numpy_to_pil(images): + """ + Convert a numpy image or a batch of images to a PIL image. + """ + if images.ndim == 3: + images = images[None, ...] + images = (images * 255).round().astype("uint8") + if images.shape[-1] == 1: + # special case for grayscale (single channel) images + pil_images = [Image.fromarray(image.squeeze(), mode="L") for image in images] + else: + pil_images = [Image.fromarray(image) for image in images] + + return pil_images + + +def make_image_grid(images: List[PIL.Image.Image], rows: int, cols: int, resize: int = None) -> PIL.Image.Image: + """ + Prepares a single grid of images. Useful for visualization purposes. + """ + assert len(images) == rows * cols + + if resize is not None: + images = [img.resize((resize, resize)) for img in images] + + w, h = images[0].size + grid = Image.new("RGB", size=(cols * w, rows * h)) + + for i, img in enumerate(images): + grid.paste(img, box=(i % cols * w, i // cols * h)) + return grid diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/remote_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/remote_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..6494dc14171a935cc7efc247f8b4870e76b575d8 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/remote_utils.py @@ -0,0 +1,425 @@ +# coding=utf-8 +# Copyright 2025 HuggingFace Inc. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import io +import json +from typing import List, Literal, Optional, Union, cast + +import requests + +from .deprecation_utils import deprecate +from .import_utils import is_safetensors_available, is_torch_available + + +if is_torch_available(): + import torch + + from ..image_processor import VaeImageProcessor + from ..video_processor import VideoProcessor + + if is_safetensors_available(): + import safetensors.torch + + DTYPE_MAP = { + "float16": torch.float16, + "float32": torch.float32, + "bfloat16": torch.bfloat16, + "uint8": torch.uint8, + } + + +from PIL import Image + + +def detect_image_type(data: bytes) -> str: + if data.startswith(b"\xff\xd8"): + return "jpeg" + elif data.startswith(b"\x89PNG\r\n\x1a\n"): + return "png" + elif data.startswith(b"GIF87a") or data.startswith(b"GIF89a"): + return "gif" + elif data.startswith(b"BM"): + return "bmp" + return "unknown" + + +def check_inputs_decode( + endpoint: str, + tensor: "torch.Tensor", + processor: Optional[Union["VaeImageProcessor", "VideoProcessor"]] = None, + do_scaling: bool = True, + scaling_factor: Optional[float] = None, + shift_factor: Optional[float] = None, + output_type: Literal["mp4", "pil", "pt"] = "pil", + return_type: Literal["mp4", "pil", "pt"] = "pil", + image_format: Literal["png", "jpg"] = "jpg", + partial_postprocess: bool = False, + input_tensor_type: Literal["binary"] = "binary", + output_tensor_type: Literal["binary"] = "binary", + height: Optional[int] = None, + width: Optional[int] = None, +): + if tensor.ndim == 3 and height is None and width is None: + raise ValueError("`height` and `width` required for packed latents.") + if ( + output_type == "pt" + and return_type == "pil" + and not partial_postprocess + and not isinstance(processor, (VaeImageProcessor, VideoProcessor)) + ): + raise ValueError("`processor` is required.") + if do_scaling and scaling_factor is None: + deprecate( + "do_scaling", + "1.0.0", + "`do_scaling` is deprecated, pass `scaling_factor` and `shift_factor` if required.", + standard_warn=False, + ) + + +def postprocess_decode( + response: requests.Response, + processor: Optional[Union["VaeImageProcessor", "VideoProcessor"]] = None, + output_type: Literal["mp4", "pil", "pt"] = "pil", + return_type: Literal["mp4", "pil", "pt"] = "pil", + partial_postprocess: bool = False, +): + if output_type == "pt" or (output_type == "pil" and processor is not None): + output_tensor = response.content + parameters = response.headers + shape = json.loads(parameters["shape"]) + dtype = parameters["dtype"] + torch_dtype = DTYPE_MAP[dtype] + output_tensor = torch.frombuffer(bytearray(output_tensor), dtype=torch_dtype).reshape(shape) + if output_type == "pt": + if partial_postprocess: + if return_type == "pil": + output = [Image.fromarray(image.numpy()) for image in output_tensor] + if len(output) == 1: + output = output[0] + elif return_type == "pt": + output = output_tensor + else: + if processor is None or return_type == "pt": + output = output_tensor + else: + if isinstance(processor, VideoProcessor): + output = cast( + List[Image.Image], + processor.postprocess_video(output_tensor, output_type="pil")[0], + ) + else: + output = cast( + Image.Image, + processor.postprocess(output_tensor, output_type="pil")[0], + ) + elif output_type == "pil" and return_type == "pil" and processor is None: + output = Image.open(io.BytesIO(response.content)).convert("RGB") + detected_format = detect_image_type(response.content) + output.format = detected_format + elif output_type == "pil" and processor is not None: + if return_type == "pil": + output = [ + Image.fromarray(image) + for image in (output_tensor.permute(0, 2, 3, 1).float().numpy() * 255).round().astype("uint8") + ] + elif return_type == "pt": + output = output_tensor + elif output_type == "mp4" and return_type == "mp4": + output = response.content + return output + + +def prepare_decode( + tensor: "torch.Tensor", + processor: Optional[Union["VaeImageProcessor", "VideoProcessor"]] = None, + do_scaling: bool = True, + scaling_factor: Optional[float] = None, + shift_factor: Optional[float] = None, + output_type: Literal["mp4", "pil", "pt"] = "pil", + image_format: Literal["png", "jpg"] = "jpg", + partial_postprocess: bool = False, + height: Optional[int] = None, + width: Optional[int] = None, +): + headers = {} + parameters = { + "image_format": image_format, + "output_type": output_type, + "partial_postprocess": partial_postprocess, + "shape": list(tensor.shape), + "dtype": str(tensor.dtype).split(".")[-1], + } + if do_scaling and scaling_factor is not None: + parameters["scaling_factor"] = scaling_factor + if do_scaling and shift_factor is not None: + parameters["shift_factor"] = shift_factor + if do_scaling and scaling_factor is None: + parameters["do_scaling"] = do_scaling + elif do_scaling and scaling_factor is None and shift_factor is None: + parameters["do_scaling"] = do_scaling + if height is not None and width is not None: + parameters["height"] = height + parameters["width"] = width + headers["Content-Type"] = "tensor/binary" + headers["Accept"] = "tensor/binary" + if output_type == "pil" and image_format == "jpg" and processor is None: + headers["Accept"] = "image/jpeg" + elif output_type == "pil" and image_format == "png" and processor is None: + headers["Accept"] = "image/png" + elif output_type == "mp4": + headers["Accept"] = "text/plain" + tensor_data = safetensors.torch._tobytes(tensor, "tensor") + return {"data": tensor_data, "params": parameters, "headers": headers} + + +def remote_decode( + endpoint: str, + tensor: "torch.Tensor", + processor: Optional[Union["VaeImageProcessor", "VideoProcessor"]] = None, + do_scaling: bool = True, + scaling_factor: Optional[float] = None, + shift_factor: Optional[float] = None, + output_type: Literal["mp4", "pil", "pt"] = "pil", + return_type: Literal["mp4", "pil", "pt"] = "pil", + image_format: Literal["png", "jpg"] = "jpg", + partial_postprocess: bool = False, + input_tensor_type: Literal["binary"] = "binary", + output_tensor_type: Literal["binary"] = "binary", + height: Optional[int] = None, + width: Optional[int] = None, +) -> Union[Image.Image, List[Image.Image], bytes, "torch.Tensor"]: + """ + Hugging Face Hybrid Inference that allow running VAE decode remotely. + + Args: + endpoint (`str`): + Endpoint for Remote Decode. + tensor (`torch.Tensor`): + Tensor to be decoded. + processor (`VaeImageProcessor` or `VideoProcessor`, *optional*): + Used with `return_type="pt"`, and `return_type="pil"` for Video models. + do_scaling (`bool`, default `True`, *optional*): + **DEPRECATED**. **pass `scaling_factor`/`shift_factor` instead.** **still set + do_scaling=None/do_scaling=False for no scaling until option is removed** When `True` scaling e.g. `latents + / self.vae.config.scaling_factor` is applied remotely. If `False`, input must be passed with scaling + applied. + scaling_factor (`float`, *optional*): + Scaling is applied when passed e.g. [`latents / + self.vae.config.scaling_factor`](https://github.com/huggingface/diffusers/blob/7007febae5cff000d4df9059d9cf35133e8b2ca9/src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion.py#L1083C37-L1083C77). + - SD v1: 0.18215 + - SD XL: 0.13025 + - Flux: 0.3611 + If `None`, input must be passed with scaling applied. + shift_factor (`float`, *optional*): + Shift is applied when passed e.g. `latents + self.vae.config.shift_factor`. + - Flux: 0.1159 + If `None`, input must be passed with scaling applied. + output_type (`"mp4"` or `"pil"` or `"pt", default `"pil"): + **Endpoint** output type. Subject to change. Report feedback on preferred type. + + `"mp4": Supported by video models. Endpoint returns `bytes` of video. `"pil"`: Supported by image and video + models. + Image models: Endpoint returns `bytes` of an image in `image_format`. Video models: Endpoint returns + `torch.Tensor` with partial `postprocessing` applied. + Requires `processor` as a flag (any `None` value will work). + `"pt"`: Support by image and video models. Endpoint returns `torch.Tensor`. + With `partial_postprocess=True` the tensor is postprocessed `uint8` image tensor. + + Recommendations: + `"pt"` with `partial_postprocess=True` is the smallest transfer for full quality. `"pt"` with + `partial_postprocess=False` is the most compatible with third party code. `"pil"` with + `image_format="jpg"` is the smallest transfer overall. + + return_type (`"mp4"` or `"pil"` or `"pt", default `"pil"): + **Function** return type. + + `"mp4": Function returns `bytes` of video. `"pil"`: Function returns `PIL.Image.Image`. + With `output_type="pil" no further processing is applied. With `output_type="pt" a `PIL.Image.Image` is + created. + `partial_postprocess=False` `processor` is required. `partial_postprocess=True` `processor` is + **not** required. + `"pt"`: Function returns `torch.Tensor`. + `processor` is **not** required. `partial_postprocess=False` tensor is `float16` or `bfloat16`, without + denormalization. `partial_postprocess=True` tensor is `uint8`, denormalized. + + image_format (`"png"` or `"jpg"`, default `jpg`): + Used with `output_type="pil"`. Endpoint returns `jpg` or `png`. + + partial_postprocess (`bool`, default `False`): + Used with `output_type="pt"`. `partial_postprocess=False` tensor is `float16` or `bfloat16`, without + denormalization. `partial_postprocess=True` tensor is `uint8`, denormalized. + + input_tensor_type (`"binary"`, default `"binary"`): + Tensor transfer type. + + output_tensor_type (`"binary"`, default `"binary"`): + Tensor transfer type. + + height (`int`, **optional**): + Required for `"packed"` latents. + + width (`int`, **optional**): + Required for `"packed"` latents. + + Returns: + output (`Image.Image` or `List[Image.Image]` or `bytes` or `torch.Tensor`). + """ + if input_tensor_type == "base64": + deprecate( + "input_tensor_type='base64'", + "1.0.0", + "input_tensor_type='base64' is deprecated. Using `binary`.", + standard_warn=False, + ) + input_tensor_type = "binary" + if output_tensor_type == "base64": + deprecate( + "output_tensor_type='base64'", + "1.0.0", + "output_tensor_type='base64' is deprecated. Using `binary`.", + standard_warn=False, + ) + output_tensor_type = "binary" + check_inputs_decode( + endpoint, + tensor, + processor, + do_scaling, + scaling_factor, + shift_factor, + output_type, + return_type, + image_format, + partial_postprocess, + input_tensor_type, + output_tensor_type, + height, + width, + ) + kwargs = prepare_decode( + tensor=tensor, + processor=processor, + do_scaling=do_scaling, + scaling_factor=scaling_factor, + shift_factor=shift_factor, + output_type=output_type, + image_format=image_format, + partial_postprocess=partial_postprocess, + height=height, + width=width, + ) + response = requests.post(endpoint, **kwargs) + if not response.ok: + raise RuntimeError(response.json()) + output = postprocess_decode( + response=response, + processor=processor, + output_type=output_type, + return_type=return_type, + partial_postprocess=partial_postprocess, + ) + return output + + +def check_inputs_encode( + endpoint: str, + image: Union["torch.Tensor", Image.Image], + scaling_factor: Optional[float] = None, + shift_factor: Optional[float] = None, +): + pass + + +def postprocess_encode( + response: requests.Response, +): + output_tensor = response.content + parameters = response.headers + shape = json.loads(parameters["shape"]) + dtype = parameters["dtype"] + torch_dtype = DTYPE_MAP[dtype] + output_tensor = torch.frombuffer(bytearray(output_tensor), dtype=torch_dtype).reshape(shape) + return output_tensor + + +def prepare_encode( + image: Union["torch.Tensor", Image.Image], + scaling_factor: Optional[float] = None, + shift_factor: Optional[float] = None, +): + headers = {} + parameters = {} + if scaling_factor is not None: + parameters["scaling_factor"] = scaling_factor + if shift_factor is not None: + parameters["shift_factor"] = shift_factor + if isinstance(image, torch.Tensor): + data = safetensors.torch._tobytes(image.contiguous(), "tensor") + parameters["shape"] = list(image.shape) + parameters["dtype"] = str(image.dtype).split(".")[-1] + else: + buffer = io.BytesIO() + image.save(buffer, format="PNG") + data = buffer.getvalue() + return {"data": data, "params": parameters, "headers": headers} + + +def remote_encode( + endpoint: str, + image: Union["torch.Tensor", Image.Image], + scaling_factor: Optional[float] = None, + shift_factor: Optional[float] = None, +) -> "torch.Tensor": + """ + Hugging Face Hybrid Inference that allow running VAE encode remotely. + + Args: + endpoint (`str`): + Endpoint for Remote Decode. + image (`torch.Tensor` or `PIL.Image.Image`): + Image to be encoded. + scaling_factor (`float`, *optional*): + Scaling is applied when passed e.g. [`latents * self.vae.config.scaling_factor`]. + - SD v1: 0.18215 + - SD XL: 0.13025 + - Flux: 0.3611 + If `None`, input must be passed with scaling applied. + shift_factor (`float`, *optional*): + Shift is applied when passed e.g. `latents - self.vae.config.shift_factor`. + - Flux: 0.1159 + If `None`, input must be passed with scaling applied. + + Returns: + output (`torch.Tensor`). + """ + check_inputs_encode( + endpoint, + image, + scaling_factor, + shift_factor, + ) + kwargs = prepare_encode( + image=image, + scaling_factor=scaling_factor, + shift_factor=shift_factor, + ) + response = requests.post(endpoint, **kwargs) + if not response.ok: + raise RuntimeError(response.json()) + output = postprocess_encode( + response=response, + ) + return output diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/source_code_parsing_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/source_code_parsing_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..5f94711c21d825f4baa0b32bbc37fd94c89aba03 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/source_code_parsing_utils.py @@ -0,0 +1,52 @@ +import ast +import importlib +import inspect +import textwrap + + +class ReturnNameVisitor(ast.NodeVisitor): + """Thanks to ChatGPT for pairing.""" + + def __init__(self): + self.return_names = [] + + def visit_Return(self, node): + # Check if the return value is a tuple. + if isinstance(node.value, ast.Tuple): + for elt in node.value.elts: + if isinstance(elt, ast.Name): + self.return_names.append(elt.id) + else: + try: + self.return_names.append(ast.unparse(elt)) + except Exception: + self.return_names.append(str(elt)) + else: + if isinstance(node.value, ast.Name): + self.return_names.append(node.value.id) + else: + try: + self.return_names.append(ast.unparse(node.value)) + except Exception: + self.return_names.append(str(node.value)) + self.generic_visit(node) + + def _determine_parent_module(self, cls): + from diffusers import DiffusionPipeline + from diffusers.models.modeling_utils import ModelMixin + + if issubclass(cls, DiffusionPipeline): + return "pipelines" + elif issubclass(cls, ModelMixin): + return "models" + else: + raise NotImplementedError + + def get_ast_tree(self, cls, attribute_name="encode_prompt"): + parent_module_name = self._determine_parent_module(cls) + main_module = importlib.import_module(f"diffusers.{parent_module_name}") + current_cls_module = getattr(main_module, cls.__name__) + source_code = inspect.getsource(getattr(current_cls_module, attribute_name)) + source_code = textwrap.dedent(source_code) + tree = ast.parse(source_code) + return tree diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/state_dict_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/state_dict_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..15a91040c48c762939897a5f7e85d3866c450e1f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/state_dict_utils.py @@ -0,0 +1,349 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +State dict utilities: utility methods for converting state dicts easily +""" + +import enum + +from .import_utils import is_torch_available +from .logging import get_logger + + +if is_torch_available(): + import torch + + +logger = get_logger(__name__) + + +class StateDictType(enum.Enum): + """ + The mode to use when converting state dicts. + """ + + DIFFUSERS_OLD = "diffusers_old" + KOHYA_SS = "kohya_ss" + PEFT = "peft" + DIFFUSERS = "diffusers" + + +# We need to define a proper mapping for Unet since it uses different output keys than text encoder +# e.g. to_q_lora -> q_proj / to_q +UNET_TO_DIFFUSERS = { + ".to_out_lora.up": ".to_out.0.lora_B", + ".to_out_lora.down": ".to_out.0.lora_A", + ".to_q_lora.down": ".to_q.lora_A", + ".to_q_lora.up": ".to_q.lora_B", + ".to_k_lora.down": ".to_k.lora_A", + ".to_k_lora.up": ".to_k.lora_B", + ".to_v_lora.down": ".to_v.lora_A", + ".to_v_lora.up": ".to_v.lora_B", + ".lora.up": ".lora_B", + ".lora.down": ".lora_A", + ".to_out.lora_magnitude_vector": ".to_out.0.lora_magnitude_vector", +} + + +DIFFUSERS_TO_PEFT = { + ".q_proj.lora_linear_layer.up": ".q_proj.lora_B", + ".q_proj.lora_linear_layer.down": ".q_proj.lora_A", + ".k_proj.lora_linear_layer.up": ".k_proj.lora_B", + ".k_proj.lora_linear_layer.down": ".k_proj.lora_A", + ".v_proj.lora_linear_layer.up": ".v_proj.lora_B", + ".v_proj.lora_linear_layer.down": ".v_proj.lora_A", + ".out_proj.lora_linear_layer.up": ".out_proj.lora_B", + ".out_proj.lora_linear_layer.down": ".out_proj.lora_A", + ".lora_linear_layer.up": ".lora_B", + ".lora_linear_layer.down": ".lora_A", + "text_projection.lora.down.weight": "text_projection.lora_A.weight", + "text_projection.lora.up.weight": "text_projection.lora_B.weight", +} + +DIFFUSERS_OLD_TO_PEFT = { + ".to_q_lora.up": ".q_proj.lora_B", + ".to_q_lora.down": ".q_proj.lora_A", + ".to_k_lora.up": ".k_proj.lora_B", + ".to_k_lora.down": ".k_proj.lora_A", + ".to_v_lora.up": ".v_proj.lora_B", + ".to_v_lora.down": ".v_proj.lora_A", + ".to_out_lora.up": ".out_proj.lora_B", + ".to_out_lora.down": ".out_proj.lora_A", + ".lora_linear_layer.up": ".lora_B", + ".lora_linear_layer.down": ".lora_A", +} + +PEFT_TO_DIFFUSERS = { + ".q_proj.lora_B": ".q_proj.lora_linear_layer.up", + ".q_proj.lora_A": ".q_proj.lora_linear_layer.down", + ".k_proj.lora_B": ".k_proj.lora_linear_layer.up", + ".k_proj.lora_A": ".k_proj.lora_linear_layer.down", + ".v_proj.lora_B": ".v_proj.lora_linear_layer.up", + ".v_proj.lora_A": ".v_proj.lora_linear_layer.down", + ".out_proj.lora_B": ".out_proj.lora_linear_layer.up", + ".out_proj.lora_A": ".out_proj.lora_linear_layer.down", + "to_k.lora_A": "to_k.lora.down", + "to_k.lora_B": "to_k.lora.up", + "to_q.lora_A": "to_q.lora.down", + "to_q.lora_B": "to_q.lora.up", + "to_v.lora_A": "to_v.lora.down", + "to_v.lora_B": "to_v.lora.up", + "to_out.0.lora_A": "to_out.0.lora.down", + "to_out.0.lora_B": "to_out.0.lora.up", +} + +DIFFUSERS_OLD_TO_DIFFUSERS = { + ".to_q_lora.up": ".q_proj.lora_linear_layer.up", + ".to_q_lora.down": ".q_proj.lora_linear_layer.down", + ".to_k_lora.up": ".k_proj.lora_linear_layer.up", + ".to_k_lora.down": ".k_proj.lora_linear_layer.down", + ".to_v_lora.up": ".v_proj.lora_linear_layer.up", + ".to_v_lora.down": ".v_proj.lora_linear_layer.down", + ".to_out_lora.up": ".out_proj.lora_linear_layer.up", + ".to_out_lora.down": ".out_proj.lora_linear_layer.down", + ".to_k.lora_magnitude_vector": ".k_proj.lora_magnitude_vector", + ".to_v.lora_magnitude_vector": ".v_proj.lora_magnitude_vector", + ".to_q.lora_magnitude_vector": ".q_proj.lora_magnitude_vector", + ".to_out.lora_magnitude_vector": ".out_proj.lora_magnitude_vector", +} + +PEFT_TO_KOHYA_SS = { + "lora_A": "lora_down", + "lora_B": "lora_up", + # This is not a comprehensive dict as kohya format requires replacing `.` with `_` in keys, + # adding prefixes and adding alpha values + # Check `convert_state_dict_to_kohya` for more +} + +PEFT_STATE_DICT_MAPPINGS = { + StateDictType.DIFFUSERS_OLD: DIFFUSERS_OLD_TO_PEFT, + StateDictType.DIFFUSERS: DIFFUSERS_TO_PEFT, +} + +DIFFUSERS_STATE_DICT_MAPPINGS = { + StateDictType.DIFFUSERS_OLD: DIFFUSERS_OLD_TO_DIFFUSERS, + StateDictType.PEFT: PEFT_TO_DIFFUSERS, +} + +KOHYA_STATE_DICT_MAPPINGS = {StateDictType.PEFT: PEFT_TO_KOHYA_SS} + +KEYS_TO_ALWAYS_REPLACE = { + ".processor.": ".", +} + + +def convert_state_dict(state_dict, mapping): + r""" + Simply iterates over the state dict and replaces the patterns in `mapping` with the corresponding values. + + Args: + state_dict (`dict[str, torch.Tensor]`): + The state dict to convert. + mapping (`dict[str, str]`): + The mapping to use for conversion, the mapping should be a dictionary with the following structure: + - key: the pattern to replace + - value: the pattern to replace with + + Returns: + converted_state_dict (`dict`) + The converted state dict. + """ + converted_state_dict = {} + for k, v in state_dict.items(): + # First, filter out the keys that we always want to replace + for pattern in KEYS_TO_ALWAYS_REPLACE.keys(): + if pattern in k: + new_pattern = KEYS_TO_ALWAYS_REPLACE[pattern] + k = k.replace(pattern, new_pattern) + + for pattern in mapping.keys(): + if pattern in k: + new_pattern = mapping[pattern] + k = k.replace(pattern, new_pattern) + break + converted_state_dict[k] = v + return converted_state_dict + + +def convert_state_dict_to_peft(state_dict, original_type=None, **kwargs): + r""" + Converts a state dict to the PEFT format The state dict can be from previous diffusers format (`OLD_DIFFUSERS`), or + new diffusers format (`DIFFUSERS`). The method only supports the conversion from diffusers old/new to PEFT for now. + + Args: + state_dict (`dict[str, torch.Tensor]`): + The state dict to convert. + original_type (`StateDictType`, *optional*): + The original type of the state dict, if not provided, the method will try to infer it automatically. + """ + if original_type is None: + # Old diffusers to PEFT + if any("to_out_lora" in k for k in state_dict.keys()): + original_type = StateDictType.DIFFUSERS_OLD + elif any("lora_linear_layer" in k for k in state_dict.keys()): + original_type = StateDictType.DIFFUSERS + else: + raise ValueError("Could not automatically infer state dict type") + + if original_type not in PEFT_STATE_DICT_MAPPINGS.keys(): + raise ValueError(f"Original type {original_type} is not supported") + + mapping = PEFT_STATE_DICT_MAPPINGS[original_type] + return convert_state_dict(state_dict, mapping) + + +def convert_state_dict_to_diffusers(state_dict, original_type=None, **kwargs): + r""" + Converts a state dict to new diffusers format. The state dict can be from previous diffusers format + (`OLD_DIFFUSERS`), or PEFT format (`PEFT`) or new diffusers format (`DIFFUSERS`). In the last case the method will + return the state dict as is. + + The method only supports the conversion from diffusers old, PEFT to diffusers new for now. + + Args: + state_dict (`dict[str, torch.Tensor]`): + The state dict to convert. + original_type (`StateDictType`, *optional*): + The original type of the state dict, if not provided, the method will try to infer it automatically. + kwargs (`dict`, *args*): + Additional arguments to pass to the method. + + - **adapter_name**: For example, in case of PEFT, some keys will be prepended + with the adapter name, therefore needs a special handling. By default PEFT also takes care of that in + `get_peft_model_state_dict` method: + https://github.com/huggingface/peft/blob/ba0477f2985b1ba311b83459d29895c809404e99/src/peft/utils/save_and_load.py#L92 + but we add it here in case we don't want to rely on that method. + """ + peft_adapter_name = kwargs.pop("adapter_name", None) + if peft_adapter_name is not None: + peft_adapter_name = "." + peft_adapter_name + else: + peft_adapter_name = "" + + if original_type is None: + # Old diffusers to PEFT + if any("to_out_lora" in k for k in state_dict.keys()): + original_type = StateDictType.DIFFUSERS_OLD + elif any(f".lora_A{peft_adapter_name}.weight" in k for k in state_dict.keys()): + original_type = StateDictType.PEFT + elif any("lora_linear_layer" in k for k in state_dict.keys()): + # nothing to do + return state_dict + else: + raise ValueError("Could not automatically infer state dict type") + + if original_type not in DIFFUSERS_STATE_DICT_MAPPINGS.keys(): + raise ValueError(f"Original type {original_type} is not supported") + + mapping = DIFFUSERS_STATE_DICT_MAPPINGS[original_type] + return convert_state_dict(state_dict, mapping) + + +def convert_unet_state_dict_to_peft(state_dict): + r""" + Converts a state dict from UNet format to diffusers format - i.e. by removing some keys + """ + mapping = UNET_TO_DIFFUSERS + return convert_state_dict(state_dict, mapping) + + +def convert_all_state_dict_to_peft(state_dict): + r""" + Attempts to first `convert_state_dict_to_peft`, and if it doesn't detect `lora_linear_layer` for a valid + `DIFFUSERS` LoRA for example, attempts to exclusively convert the Unet `convert_unet_state_dict_to_peft` + """ + try: + peft_dict = convert_state_dict_to_peft(state_dict) + except Exception as e: + if str(e) == "Could not automatically infer state dict type": + peft_dict = convert_unet_state_dict_to_peft(state_dict) + else: + raise + + if not any("lora_A" in key or "lora_B" in key for key in peft_dict.keys()): + raise ValueError("Your LoRA was not converted to PEFT") + + return peft_dict + + +def convert_state_dict_to_kohya(state_dict, original_type=None, **kwargs): + r""" + Converts a `PEFT` state dict to `Kohya` format that can be used in AUTOMATIC1111, ComfyUI, SD.Next, InvokeAI, etc. + The method only supports the conversion from PEFT to Kohya for now. + + Args: + state_dict (`dict[str, torch.Tensor]`): + The state dict to convert. + original_type (`StateDictType`, *optional*): + The original type of the state dict, if not provided, the method will try to infer it automatically. + kwargs (`dict`, *args*): + Additional arguments to pass to the method. + + - **adapter_name**: For example, in case of PEFT, some keys will be prepended + with the adapter name, therefore needs a special handling. By default PEFT also takes care of that in + `get_peft_model_state_dict` method: + https://github.com/huggingface/peft/blob/ba0477f2985b1ba311b83459d29895c809404e99/src/peft/utils/save_and_load.py#L92 + but we add it here in case we don't want to rely on that method. + """ + try: + import torch + except ImportError: + logger.error("Converting PEFT state dicts to Kohya requires torch to be installed.") + raise + + peft_adapter_name = kwargs.pop("adapter_name", None) + if peft_adapter_name is not None: + peft_adapter_name = "." + peft_adapter_name + else: + peft_adapter_name = "" + + if original_type is None: + if any(f".lora_A{peft_adapter_name}.weight" in k for k in state_dict.keys()): + original_type = StateDictType.PEFT + + if original_type not in KOHYA_STATE_DICT_MAPPINGS.keys(): + raise ValueError(f"Original type {original_type} is not supported") + + # Use the convert_state_dict function with the appropriate mapping + kohya_ss_partial_state_dict = convert_state_dict(state_dict, KOHYA_STATE_DICT_MAPPINGS[StateDictType.PEFT]) + kohya_ss_state_dict = {} + + # Additional logic for replacing header, alpha parameters `.` with `_` in all keys + for kohya_key, weight in kohya_ss_partial_state_dict.items(): + if "text_encoder_2." in kohya_key: + kohya_key = kohya_key.replace("text_encoder_2.", "lora_te2.") + elif "text_encoder." in kohya_key: + kohya_key = kohya_key.replace("text_encoder.", "lora_te1.") + elif "unet" in kohya_key: + kohya_key = kohya_key.replace("unet", "lora_unet") + elif "lora_magnitude_vector" in kohya_key: + kohya_key = kohya_key.replace("lora_magnitude_vector", "dora_scale") + + kohya_key = kohya_key.replace(".", "_", kohya_key.count(".") - 2) + kohya_key = kohya_key.replace(peft_adapter_name, "") # Kohya doesn't take names + kohya_ss_state_dict[kohya_key] = weight + if "lora_down" in kohya_key: + alpha_key = f"{kohya_key.split('.')[0]}.alpha" + kohya_ss_state_dict[alpha_key] = torch.tensor(len(weight)) + + return kohya_ss_state_dict + + +def state_dict_all_zero(state_dict, filter_str=None): + if filter_str is not None: + if isinstance(filter_str, str): + filter_str = [filter_str] + state_dict = {k: v for k, v in state_dict.items() if any(f in k for f in filter_str)} + + return all(torch.all(param == 0).item() for param in state_dict.values()) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/testing_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/testing_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..e19a9f83fdb923bf0fcbb49a9e0236e5a1f00745 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/testing_utils.py @@ -0,0 +1,1398 @@ +import functools +import importlib +import importlib.metadata +import inspect +import io +import logging +import multiprocessing +import os +import random +import re +import struct +import sys +import tempfile +import time +import unittest +import urllib.parse +from collections import UserDict +from contextlib import contextmanager +from io import BytesIO, StringIO +from pathlib import Path +from typing import TYPE_CHECKING, Any, Callable, Dict, List, Optional, Tuple, Union + +import numpy as np +import PIL.Image +import PIL.ImageOps +import requests +from numpy.linalg import norm +from packaging import version + +from .constants import DIFFUSERS_REQUEST_TIMEOUT +from .import_utils import ( + BACKENDS_MAPPING, + is_accelerate_available, + is_bitsandbytes_available, + is_compel_available, + is_flax_available, + is_gguf_available, + is_note_seq_available, + is_onnx_available, + is_opencv_available, + is_optimum_quanto_available, + is_peft_available, + is_timm_available, + is_torch_available, + is_torch_version, + is_torchao_available, + is_torchsde_available, + is_transformers_available, +) +from .logging import get_logger + + +if is_torch_available(): + import torch + + IS_ROCM_SYSTEM = torch.version.hip is not None + IS_CUDA_SYSTEM = torch.version.cuda is not None + IS_XPU_SYSTEM = getattr(torch.version, "xpu", None) is not None +else: + IS_ROCM_SYSTEM = False + IS_CUDA_SYSTEM = False + IS_XPU_SYSTEM = False + +global_rng = random.Random() + +logger = get_logger(__name__) + +_required_peft_version = is_peft_available() and version.parse( + version.parse(importlib.metadata.version("peft")).base_version +) > version.parse("0.5") +_required_transformers_version = is_transformers_available() and version.parse( + version.parse(importlib.metadata.version("transformers")).base_version +) > version.parse("4.33") + +USE_PEFT_BACKEND = _required_peft_version and _required_transformers_version +BIG_GPU_MEMORY = int(os.getenv("BIG_GPU_MEMORY", 40)) + +if is_torch_available(): + import torch + + # Set a backend environment variable for any extra module import required for a custom accelerator + if "DIFFUSERS_TEST_BACKEND" in os.environ: + backend = os.environ["DIFFUSERS_TEST_BACKEND"] + try: + _ = importlib.import_module(backend) + except ModuleNotFoundError as e: + raise ModuleNotFoundError( + f"Failed to import `DIFFUSERS_TEST_BACKEND` '{backend}'! This should be the name of an installed module \ + to enable a specified backend.):\n{e}" + ) from e + + if "DIFFUSERS_TEST_DEVICE" in os.environ: + torch_device = os.environ["DIFFUSERS_TEST_DEVICE"] + try: + # try creating device to see if provided device is valid + _ = torch.device(torch_device) + except RuntimeError as e: + raise RuntimeError( + f"Unknown testing device specified by environment variable `DIFFUSERS_TEST_DEVICE`: {torch_device}" + ) from e + logger.info(f"torch_device overrode to {torch_device}") + else: + if torch.cuda.is_available(): + torch_device = "cuda" + elif torch.xpu.is_available(): + torch_device = "xpu" + else: + torch_device = "cpu" + is_torch_higher_equal_than_1_12 = version.parse( + version.parse(torch.__version__).base_version + ) >= version.parse("1.12") + + if is_torch_higher_equal_than_1_12: + # Some builds of torch 1.12 don't have the mps backend registered. See #892 for more details + mps_backend_registered = hasattr(torch.backends, "mps") + torch_device = "mps" if (mps_backend_registered and torch.backends.mps.is_available()) else torch_device + + from .torch_utils import get_torch_cuda_device_capability + + +def torch_all_close(a, b, *args, **kwargs): + if not is_torch_available(): + raise ValueError("PyTorch needs to be installed to use this function.") + if not torch.allclose(a, b, *args, **kwargs): + assert False, f"Max diff is absolute {(a - b).abs().max()}. Diff tensor is {(a - b).abs()}." + return True + + +def numpy_cosine_similarity_distance(a, b): + similarity = np.dot(a, b) / (norm(a) * norm(b)) + distance = 1.0 - similarity.mean() + + return distance + + +def print_tensor_test( + tensor, + limit_to_slices=None, + max_torch_print=None, + filename="test_corrections.txt", + expected_tensor_name="expected_slice", +): + if max_torch_print: + torch.set_printoptions(threshold=10_000) + + test_name = os.environ.get("PYTEST_CURRENT_TEST") + if not torch.is_tensor(tensor): + tensor = torch.from_numpy(tensor) + if limit_to_slices: + tensor = tensor[0, -3:, -3:, -1] + + tensor_str = str(tensor.detach().cpu().flatten().to(torch.float32)).replace("\n", "") + # format is usually: + # expected_slice = np.array([-0.5713, -0.3018, -0.9814, 0.04663, -0.879, 0.76, -1.734, 0.1044, 1.161]) + output_str = tensor_str.replace("tensor", f"{expected_tensor_name} = np.array") + test_file, test_class, test_fn = test_name.split("::") + test_fn = test_fn.split()[0] + with open(filename, "a") as f: + print("::".join([test_file, test_class, test_fn, output_str]), file=f) + + +def get_tests_dir(append_path=None): + """ + Args: + append_path: optional path to append to the tests dir path + Return: + The full path to the `tests` dir, so that the tests can be invoked from anywhere. Optionally `append_path` is + joined after the `tests` dir the former is provided. + """ + # this function caller's __file__ + caller__file__ = inspect.stack()[1][1] + tests_dir = os.path.abspath(os.path.dirname(caller__file__)) + + while not tests_dir.endswith("tests"): + tests_dir = os.path.dirname(tests_dir) + + if append_path: + return Path(tests_dir, append_path).as_posix() + else: + return tests_dir + + +# Taken from the following PR: +# https://github.com/huggingface/accelerate/pull/1964 +def str_to_bool(value) -> int: + """ + Converts a string representation of truth to `True` (1) or `False` (0). True values are `y`, `yes`, `t`, `true`, + `on`, and `1`; False value are `n`, `no`, `f`, `false`, `off`, and `0`; + """ + value = value.lower() + if value in ("y", "yes", "t", "true", "on", "1"): + return 1 + elif value in ("n", "no", "f", "false", "off", "0"): + return 0 + else: + raise ValueError(f"invalid truth value {value}") + + +def parse_flag_from_env(key, default=False): + try: + value = os.environ[key] + except KeyError: + # KEY isn't set, default to `default`. + _value = default + else: + # KEY is set, convert it to True or False. + try: + _value = str_to_bool(value) + except ValueError: + # More values are supported, but let's keep the message simple. + raise ValueError(f"If set, {key} must be yes or no.") + return _value + + +_run_slow_tests = parse_flag_from_env("RUN_SLOW", default=False) +_run_nightly_tests = parse_flag_from_env("RUN_NIGHTLY", default=False) +_run_compile_tests = parse_flag_from_env("RUN_COMPILE", default=False) + + +def floats_tensor(shape, scale=1.0, rng=None, name=None): + """Creates a random float32 tensor""" + if rng is None: + rng = global_rng + + total_dims = 1 + for dim in shape: + total_dims *= dim + + values = [] + for _ in range(total_dims): + values.append(rng.random() * scale) + + return torch.tensor(data=values, dtype=torch.float).view(shape).contiguous() + + +def slow(test_case): + """ + Decorator marking a test as slow. + + Slow tests are skipped by default. Set the RUN_SLOW environment variable to a truthy value to run them. + + """ + return unittest.skipUnless(_run_slow_tests, "test is slow")(test_case) + + +def nightly(test_case): + """ + Decorator marking a test that runs nightly in the diffusers CI. + + Slow tests are skipped by default. Set the RUN_NIGHTLY environment variable to a truthy value to run them. + + """ + return unittest.skipUnless(_run_nightly_tests, "test is nightly")(test_case) + + +def is_torch_compile(test_case): + """ + Decorator marking a test that runs compile tests in the diffusers CI. + + Compile tests are skipped by default. Set the RUN_COMPILE environment variable to a truthy value to run them. + + """ + return unittest.skipUnless(_run_compile_tests, "test is torch compile")(test_case) + + +def require_torch(test_case): + """ + Decorator marking a test that requires PyTorch. These tests are skipped when PyTorch isn't installed. + """ + return unittest.skipUnless(is_torch_available(), "test requires PyTorch")(test_case) + + +def require_torch_2(test_case): + """ + Decorator marking a test that requires PyTorch 2. These tests are skipped when it isn't installed. + """ + return unittest.skipUnless(is_torch_available() and is_torch_version(">=", "2.0.0"), "test requires PyTorch 2")( + test_case + ) + + +def require_torch_version_greater_equal(torch_version): + """Decorator marking a test that requires torch with a specific version or greater.""" + + def decorator(test_case): + correct_torch_version = is_torch_available() and is_torch_version(">=", torch_version) + return unittest.skipUnless( + correct_torch_version, f"test requires torch with the version greater than or equal to {torch_version}" + )(test_case) + + return decorator + + +def require_torch_gpu(test_case): + """Decorator marking a test that requires CUDA and PyTorch.""" + return unittest.skipUnless(is_torch_available() and torch_device == "cuda", "test requires PyTorch+CUDA")( + test_case + ) + + +def require_torch_cuda_compatibility(expected_compute_capability): + def decorator(test_case): + if not torch.cuda.is_available(): + return unittest.skip(test_case) + else: + current_compute_capability = get_torch_cuda_device_capability() + return unittest.skipUnless( + float(current_compute_capability) == float(expected_compute_capability), + "Test not supported for this compute capability.", + ) + + return decorator + + +# These decorators are for accelerator-specific behaviours that are not GPU-specific +def require_torch_accelerator(test_case): + """Decorator marking a test that requires an accelerator backend and PyTorch.""" + return unittest.skipUnless(is_torch_available() and torch_device != "cpu", "test requires accelerator+PyTorch")( + test_case + ) + + +def require_torch_multi_gpu(test_case): + """ + Decorator marking a test that requires a multi-GPU setup (in PyTorch). These tests are skipped on a machine without + multiple GPUs. To run *only* the multi_gpu tests, assuming all test names contain multi_gpu: $ pytest -sv ./tests + -k "multi_gpu" + """ + if not is_torch_available(): + return unittest.skip("test requires PyTorch")(test_case) + + import torch + + return unittest.skipUnless(torch.cuda.device_count() > 1, "test requires multiple GPUs")(test_case) + + +def require_torch_multi_accelerator(test_case): + """ + Decorator marking a test that requires a multi-accelerator setup (in PyTorch). These tests are skipped on a machine + without multiple hardware accelerators. + """ + if not is_torch_available(): + return unittest.skip("test requires PyTorch")(test_case) + + import torch + + return unittest.skipUnless( + torch.cuda.device_count() > 1 or torch.xpu.device_count() > 1, "test requires multiple hardware accelerators" + )(test_case) + + +def require_torch_accelerator_with_fp16(test_case): + """Decorator marking a test that requires an accelerator with support for the FP16 data type.""" + return unittest.skipUnless(_is_torch_fp16_available(torch_device), "test requires accelerator with fp16 support")( + test_case + ) + + +def require_torch_accelerator_with_fp64(test_case): + """Decorator marking a test that requires an accelerator with support for the FP64 data type.""" + return unittest.skipUnless(_is_torch_fp64_available(torch_device), "test requires accelerator with fp64 support")( + test_case + ) + + +def require_big_gpu_with_torch_cuda(test_case): + """ + Decorator marking a test that requires a bigger GPU (24GB) for execution. Some example pipelines: Flux, SD3, Cog, + etc. + """ + if not is_torch_available(): + return unittest.skip("test requires PyTorch")(test_case) + + import torch + + if not torch.cuda.is_available(): + return unittest.skip("test requires PyTorch CUDA")(test_case) + + device_properties = torch.cuda.get_device_properties(0) + total_memory = device_properties.total_memory / (1024**3) + return unittest.skipUnless( + total_memory >= BIG_GPU_MEMORY, f"test requires a GPU with at least {BIG_GPU_MEMORY} GB memory" + )(test_case) + + +def require_big_accelerator(test_case): + """ + Decorator marking a test that requires a bigger hardware accelerator (24GB) for execution. Some example pipelines: + Flux, SD3, Cog, etc. + """ + if not is_torch_available(): + return unittest.skip("test requires PyTorch")(test_case) + + import torch + + if not (torch.cuda.is_available() or torch.xpu.is_available()): + return unittest.skip("test requires PyTorch CUDA")(test_case) + + if torch.xpu.is_available(): + device_properties = torch.xpu.get_device_properties(0) + else: + device_properties = torch.cuda.get_device_properties(0) + + total_memory = device_properties.total_memory / (1024**3) + return unittest.skipUnless( + total_memory >= BIG_GPU_MEMORY, + f"test requires a hardware accelerator with at least {BIG_GPU_MEMORY} GB memory", + )(test_case) + + +def require_torch_accelerator_with_training(test_case): + """Decorator marking a test that requires an accelerator with support for training.""" + return unittest.skipUnless( + is_torch_available() and backend_supports_training(torch_device), + "test requires accelerator with training support", + )(test_case) + + +def skip_mps(test_case): + """Decorator marking a test to skip if torch_device is 'mps'""" + return unittest.skipUnless(torch_device != "mps", "test requires non 'mps' device")(test_case) + + +def require_flax(test_case): + """ + Decorator marking a test that requires JAX & Flax. These tests are skipped when one / both are not installed + """ + return unittest.skipUnless(is_flax_available(), "test requires JAX & Flax")(test_case) + + +def require_compel(test_case): + """ + Decorator marking a test that requires compel: https://github.com/damian0815/compel. These tests are skipped when + the library is not installed. + """ + return unittest.skipUnless(is_compel_available(), "test requires compel")(test_case) + + +def require_onnxruntime(test_case): + """ + Decorator marking a test that requires onnxruntime. These tests are skipped when onnxruntime isn't installed. + """ + return unittest.skipUnless(is_onnx_available(), "test requires onnxruntime")(test_case) + + +def require_note_seq(test_case): + """ + Decorator marking a test that requires note_seq. These tests are skipped when note_seq isn't installed. + """ + return unittest.skipUnless(is_note_seq_available(), "test requires note_seq")(test_case) + + +def require_accelerator(test_case): + """ + Decorator marking a test that requires a hardware accelerator backend. These tests are skipped when there are no + hardware accelerator available. + """ + return unittest.skipUnless(torch_device != "cpu", "test requires a hardware accelerator")(test_case) + + +def require_torchsde(test_case): + """ + Decorator marking a test that requires torchsde. These tests are skipped when torchsde isn't installed. + """ + return unittest.skipUnless(is_torchsde_available(), "test requires torchsde")(test_case) + + +def require_peft_backend(test_case): + """ + Decorator marking a test that requires PEFT backend, this would require some specific versions of PEFT and + transformers. + """ + return unittest.skipUnless(USE_PEFT_BACKEND, "test requires PEFT backend")(test_case) + + +def require_timm(test_case): + """ + Decorator marking a test that requires timm. These tests are skipped when timm isn't installed. + """ + return unittest.skipUnless(is_timm_available(), "test requires timm")(test_case) + + +def require_bitsandbytes(test_case): + """ + Decorator marking a test that requires bitsandbytes. These tests are skipped when bitsandbytes isn't installed. + """ + return unittest.skipUnless(is_bitsandbytes_available(), "test requires bitsandbytes")(test_case) + + +def require_quanto(test_case): + """ + Decorator marking a test that requires quanto. These tests are skipped when quanto isn't installed. + """ + return unittest.skipUnless(is_optimum_quanto_available(), "test requires quanto")(test_case) + + +def require_accelerate(test_case): + """ + Decorator marking a test that requires accelerate. These tests are skipped when accelerate isn't installed. + """ + return unittest.skipUnless(is_accelerate_available(), "test requires accelerate")(test_case) + + +def require_peft_version_greater(peft_version): + """ + Decorator marking a test that requires PEFT backend with a specific version, this would require some specific + versions of PEFT and transformers. + """ + + def decorator(test_case): + correct_peft_version = is_peft_available() and version.parse( + version.parse(importlib.metadata.version("peft")).base_version + ) > version.parse(peft_version) + return unittest.skipUnless( + correct_peft_version, f"test requires PEFT backend with the version greater than {peft_version}" + )(test_case) + + return decorator + + +def require_transformers_version_greater(transformers_version): + """ + Decorator marking a test that requires transformers with a specific version, this would require some specific + versions of PEFT and transformers. + """ + + def decorator(test_case): + correct_transformers_version = is_transformers_available() and version.parse( + version.parse(importlib.metadata.version("transformers")).base_version + ) > version.parse(transformers_version) + return unittest.skipUnless( + correct_transformers_version, + f"test requires transformers with the version greater than {transformers_version}", + )(test_case) + + return decorator + + +def require_accelerate_version_greater(accelerate_version): + def decorator(test_case): + correct_accelerate_version = is_accelerate_available() and version.parse( + version.parse(importlib.metadata.version("accelerate")).base_version + ) > version.parse(accelerate_version) + return unittest.skipUnless( + correct_accelerate_version, f"Test requires accelerate with the version greater than {accelerate_version}." + )(test_case) + + return decorator + + +def require_bitsandbytes_version_greater(bnb_version): + def decorator(test_case): + correct_bnb_version = is_bitsandbytes_available() and version.parse( + version.parse(importlib.metadata.version("bitsandbytes")).base_version + ) > version.parse(bnb_version) + return unittest.skipUnless( + correct_bnb_version, f"Test requires bitsandbytes with the version greater than {bnb_version}." + )(test_case) + + return decorator + + +def require_hf_hub_version_greater(hf_hub_version): + def decorator(test_case): + correct_hf_hub_version = version.parse( + version.parse(importlib.metadata.version("huggingface_hub")).base_version + ) > version.parse(hf_hub_version) + return unittest.skipUnless( + correct_hf_hub_version, f"Test requires huggingface_hub with the version greater than {hf_hub_version}." + )(test_case) + + return decorator + + +def require_gguf_version_greater_or_equal(gguf_version): + def decorator(test_case): + correct_gguf_version = is_gguf_available() and version.parse( + version.parse(importlib.metadata.version("gguf")).base_version + ) >= version.parse(gguf_version) + return unittest.skipUnless( + correct_gguf_version, f"Test requires gguf with the version greater than {gguf_version}." + )(test_case) + + return decorator + + +def require_torchao_version_greater_or_equal(torchao_version): + def decorator(test_case): + correct_torchao_version = is_torchao_available() and version.parse( + version.parse(importlib.metadata.version("torchao")).base_version + ) >= version.parse(torchao_version) + return unittest.skipUnless( + correct_torchao_version, f"Test requires torchao with version greater than {torchao_version}." + )(test_case) + + return decorator + + +def deprecate_after_peft_backend(test_case): + """ + Decorator marking a test that will be skipped after PEFT backend + """ + return unittest.skipUnless(not USE_PEFT_BACKEND, "test skipped in favor of PEFT backend")(test_case) + + +def get_python_version(): + sys_info = sys.version_info + major, minor = sys_info.major, sys_info.minor + return major, minor + + +def load_numpy(arry: Union[str, np.ndarray], local_path: Optional[str] = None) -> np.ndarray: + if isinstance(arry, str): + if local_path is not None: + # local_path can be passed to correct images of tests + return Path(local_path, arry.split("/")[-5], arry.split("/")[-2], arry.split("/")[-1]).as_posix() + elif arry.startswith("http://") or arry.startswith("https://"): + response = requests.get(arry, timeout=DIFFUSERS_REQUEST_TIMEOUT) + response.raise_for_status() + arry = np.load(BytesIO(response.content)) + elif os.path.isfile(arry): + arry = np.load(arry) + else: + raise ValueError( + f"Incorrect path or url, URLs must start with `http://` or `https://`, and {arry} is not a valid path" + ) + elif isinstance(arry, np.ndarray): + pass + else: + raise ValueError( + "Incorrect format used for numpy ndarray. Should be an url linking to an image, a local path, or a" + " ndarray." + ) + + return arry + + +def load_pt(url: str, map_location: Optional[str] = None, weights_only: Optional[bool] = True): + response = requests.get(url, timeout=DIFFUSERS_REQUEST_TIMEOUT) + response.raise_for_status() + arry = torch.load(BytesIO(response.content), map_location=map_location, weights_only=weights_only) + return arry + + +def load_image(image: Union[str, PIL.Image.Image]) -> PIL.Image.Image: + """ + Loads `image` to a PIL Image. + + Args: + image (`str` or `PIL.Image.Image`): + The image to convert to the PIL Image format. + Returns: + `PIL.Image.Image`: + A PIL Image. + """ + if isinstance(image, str): + if image.startswith("http://") or image.startswith("https://"): + image = PIL.Image.open(requests.get(image, stream=True, timeout=DIFFUSERS_REQUEST_TIMEOUT).raw) + elif os.path.isfile(image): + image = PIL.Image.open(image) + else: + raise ValueError( + f"Incorrect path or url, URLs must start with `http://` or `https://`, and {image} is not a valid path" + ) + elif isinstance(image, PIL.Image.Image): + image = image + else: + raise ValueError( + "Incorrect format used for image. Should be an url linking to an image, a local path, or a PIL image." + ) + image = PIL.ImageOps.exif_transpose(image) + image = image.convert("RGB") + return image + + +def preprocess_image(image: PIL.Image, batch_size: int): + w, h = image.size + w, h = (x - x % 8 for x in (w, h)) # resize to integer multiple of 8 + image = image.resize((w, h), resample=PIL.Image.LANCZOS) + image = np.array(image).astype(np.float32) / 255.0 + image = np.vstack([image[None].transpose(0, 3, 1, 2)] * batch_size) + image = torch.from_numpy(image) + return 2.0 * image - 1.0 + + +def export_to_gif(image: List[PIL.Image.Image], output_gif_path: str = None) -> str: + if output_gif_path is None: + output_gif_path = tempfile.NamedTemporaryFile(suffix=".gif").name + + image[0].save( + output_gif_path, + save_all=True, + append_images=image[1:], + optimize=False, + duration=100, + loop=0, + ) + return output_gif_path + + +@contextmanager +def buffered_writer(raw_f): + f = io.BufferedWriter(raw_f) + yield f + f.flush() + + +def export_to_ply(mesh, output_ply_path: str = None): + """ + Write a PLY file for a mesh. + """ + if output_ply_path is None: + output_ply_path = tempfile.NamedTemporaryFile(suffix=".ply").name + + coords = mesh.verts.detach().cpu().numpy() + faces = mesh.faces.cpu().numpy() + rgb = np.stack([mesh.vertex_channels[x].detach().cpu().numpy() for x in "RGB"], axis=1) + + with buffered_writer(open(output_ply_path, "wb")) as f: + f.write(b"ply\n") + f.write(b"format binary_little_endian 1.0\n") + f.write(bytes(f"element vertex {len(coords)}\n", "ascii")) + f.write(b"property float x\n") + f.write(b"property float y\n") + f.write(b"property float z\n") + if rgb is not None: + f.write(b"property uchar red\n") + f.write(b"property uchar green\n") + f.write(b"property uchar blue\n") + if faces is not None: + f.write(bytes(f"element face {len(faces)}\n", "ascii")) + f.write(b"property list uchar int vertex_index\n") + f.write(b"end_header\n") + + if rgb is not None: + rgb = (rgb * 255.499).round().astype(int) + vertices = [ + (*coord, *rgb) + for coord, rgb in zip( + coords.tolist(), + rgb.tolist(), + ) + ] + format = struct.Struct("<3f3B") + for item in vertices: + f.write(format.pack(*item)) + else: + format = struct.Struct("<3f") + for vertex in coords.tolist(): + f.write(format.pack(*vertex)) + + if faces is not None: + format = struct.Struct(" str: + if is_opencv_available(): + import cv2 + else: + raise ImportError(BACKENDS_MAPPING["opencv"][1].format("export_to_video")) + if output_video_path is None: + output_video_path = tempfile.NamedTemporaryFile(suffix=".mp4").name + + fourcc = cv2.VideoWriter_fourcc(*"mp4v") + h, w, c = video_frames[0].shape + video_writer = cv2.VideoWriter(output_video_path, fourcc, fps=8, frameSize=(w, h)) + for i in range(len(video_frames)): + img = cv2.cvtColor(video_frames[i], cv2.COLOR_RGB2BGR) + video_writer.write(img) + return output_video_path + + +def load_hf_numpy(path) -> np.ndarray: + base_url = "https://huggingface.co/datasets/fusing/diffusers-testing/resolve/main" + + if not path.startswith("http://") and not path.startswith("https://"): + path = os.path.join(base_url, urllib.parse.quote(path)) + + return load_numpy(path) + + +# --- pytest conf functions --- # + +# to avoid multiple invocation from tests/conftest.py and examples/conftest.py - make sure it's called only once +pytest_opt_registered = {} + + +def pytest_addoption_shared(parser): + """ + This function is to be called from `conftest.py` via `pytest_addoption` wrapper that has to be defined there. + + It allows loading both `conftest.py` files at once without causing a failure due to adding the same `pytest` + option. + + """ + option = "--make-reports" + if option not in pytest_opt_registered: + parser.addoption( + option, + action="store", + default=False, + help="generate report files. The value of this option is used as a prefix to report names", + ) + pytest_opt_registered[option] = 1 + + +def pytest_terminal_summary_main(tr, id): + """ + Generate multiple reports at the end of test suite run - each report goes into a dedicated file in the current + directory. The report files are prefixed with the test suite name. + + This function emulates --duration and -rA pytest arguments. + + This function is to be called from `conftest.py` via `pytest_terminal_summary` wrapper that has to be defined + there. + + Args: + - tr: `terminalreporter` passed from `conftest.py` + - id: unique id like `tests` or `examples` that will be incorporated into the final reports filenames - this is + needed as some jobs have multiple runs of pytest, so we can't have them overwrite each other. + + NB: this functions taps into a private _pytest API and while unlikely, it could break should + pytest do internal changes - also it calls default internal methods of terminalreporter which + can be hijacked by various `pytest-` plugins and interfere. + + """ + from _pytest.config import create_terminal_writer + + if not len(id): + id = "tests" + + config = tr.config + orig_writer = config.get_terminal_writer() + orig_tbstyle = config.option.tbstyle + orig_reportchars = tr.reportchars + + dir = "reports" + Path(dir).mkdir(parents=True, exist_ok=True) + report_files = { + k: f"{dir}/{id}_{k}.txt" + for k in [ + "durations", + "errors", + "failures_long", + "failures_short", + "failures_line", + "passes", + "stats", + "summary_short", + "warnings", + ] + } + + # custom durations report + # note: there is no need to call pytest --durations=XX to get this separate report + # adapted from https://github.com/pytest-dev/pytest/blob/897f151e/src/_pytest/runner.py#L66 + dlist = [] + for replist in tr.stats.values(): + for rep in replist: + if hasattr(rep, "duration"): + dlist.append(rep) + if dlist: + dlist.sort(key=lambda x: x.duration, reverse=True) + with open(report_files["durations"], "w") as f: + durations_min = 0.05 # sec + f.write("slowest durations\n") + for i, rep in enumerate(dlist): + if rep.duration < durations_min: + f.write(f"{len(dlist) - i} durations < {durations_min} secs were omitted") + break + f.write(f"{rep.duration:02.2f}s {rep.when:<8} {rep.nodeid}\n") + + def summary_failures_short(tr): + # expecting that the reports were --tb=long (default) so we chop them off here to the last frame + reports = tr.getreports("failed") + if not reports: + return + tr.write_sep("=", "FAILURES SHORT STACK") + for rep in reports: + msg = tr._getfailureheadline(rep) + tr.write_sep("_", msg, red=True, bold=True) + # chop off the optional leading extra frames, leaving only the last one + longrepr = re.sub(r".*_ _ _ (_ ){10,}_ _ ", "", rep.longreprtext, 0, re.M | re.S) + tr._tw.line(longrepr) + # note: not printing out any rep.sections to keep the report short + + # use ready-made report funcs, we are just hijacking the filehandle to log to a dedicated file each + # adapted from https://github.com/pytest-dev/pytest/blob/897f151e/src/_pytest/terminal.py#L814 + # note: some pytest plugins may interfere by hijacking the default `terminalreporter` (e.g. + # pytest-instafail does that) + + # report failures with line/short/long styles + config.option.tbstyle = "auto" # full tb + with open(report_files["failures_long"], "w") as f: + tr._tw = create_terminal_writer(config, f) + tr.summary_failures() + + # config.option.tbstyle = "short" # short tb + with open(report_files["failures_short"], "w") as f: + tr._tw = create_terminal_writer(config, f) + summary_failures_short(tr) + + config.option.tbstyle = "line" # one line per error + with open(report_files["failures_line"], "w") as f: + tr._tw = create_terminal_writer(config, f) + tr.summary_failures() + + with open(report_files["errors"], "w") as f: + tr._tw = create_terminal_writer(config, f) + tr.summary_errors() + + with open(report_files["warnings"], "w") as f: + tr._tw = create_terminal_writer(config, f) + tr.summary_warnings() # normal warnings + tr.summary_warnings() # final warnings + + tr.reportchars = "wPpsxXEf" # emulate -rA (used in summary_passes() and short_test_summary()) + with open(report_files["passes"], "w") as f: + tr._tw = create_terminal_writer(config, f) + tr.summary_passes() + + with open(report_files["summary_short"], "w") as f: + tr._tw = create_terminal_writer(config, f) + tr.short_test_summary() + + with open(report_files["stats"], "w") as f: + tr._tw = create_terminal_writer(config, f) + tr.summary_stats() + + # restore: + tr._tw = orig_writer + tr.reportchars = orig_reportchars + config.option.tbstyle = orig_tbstyle + + +# Copied from https://github.com/huggingface/transformers/blob/000e52aec8850d3fe2f360adc6fd256e5b47fe4c/src/transformers/testing_utils.py#L1905 +def is_flaky(max_attempts: int = 5, wait_before_retry: Optional[float] = None, description: Optional[str] = None): + """ + To decorate flaky tests. They will be retried on failures. + + Args: + max_attempts (`int`, *optional*, defaults to 5): + The maximum number of attempts to retry the flaky test. + wait_before_retry (`float`, *optional*): + If provided, will wait that number of seconds before retrying the test. + description (`str`, *optional*): + A string to describe the situation (what / where / why is flaky, link to GH issue/PR comments, errors, + etc.) + """ + + def decorator(test_func_ref): + @functools.wraps(test_func_ref) + def wrapper(*args, **kwargs): + retry_count = 1 + + while retry_count < max_attempts: + try: + return test_func_ref(*args, **kwargs) + + except Exception as err: + print(f"Test failed with {err} at try {retry_count}/{max_attempts}.", file=sys.stderr) + if wait_before_retry is not None: + time.sleep(wait_before_retry) + retry_count += 1 + + return test_func_ref(*args, **kwargs) + + return wrapper + + return decorator + + +# Taken from: https://github.com/huggingface/transformers/blob/3658488ff77ff8d45101293e749263acf437f4d5/src/transformers/testing_utils.py#L1787 +def run_test_in_subprocess(test_case, target_func, inputs=None, timeout=None): + """ + To run a test in a subprocess. In particular, this can avoid (GPU) memory issue. + + Args: + test_case (`unittest.TestCase`): + The test that will run `target_func`. + target_func (`Callable`): + The function implementing the actual testing logic. + inputs (`dict`, *optional*, defaults to `None`): + The inputs that will be passed to `target_func` through an (input) queue. + timeout (`int`, *optional*, defaults to `None`): + The timeout (in seconds) that will be passed to the input and output queues. If not specified, the env. + variable `PYTEST_TIMEOUT` will be checked. If still `None`, its value will be set to `600`. + """ + if timeout is None: + timeout = int(os.environ.get("PYTEST_TIMEOUT", 600)) + + start_methohd = "spawn" + ctx = multiprocessing.get_context(start_methohd) + + input_queue = ctx.Queue(1) + output_queue = ctx.JoinableQueue(1) + + # We can't send `unittest.TestCase` to the child, otherwise we get issues regarding pickle. + input_queue.put(inputs, timeout=timeout) + + process = ctx.Process(target=target_func, args=(input_queue, output_queue, timeout)) + process.start() + # Kill the child process if we can't get outputs from it in time: otherwise, the hanging subprocess prevents + # the test to exit properly. + try: + results = output_queue.get(timeout=timeout) + output_queue.task_done() + except Exception as e: + process.terminate() + test_case.fail(e) + process.join(timeout=timeout) + + if results["error"] is not None: + test_case.fail(f"{results['error']}") + + +class CaptureLogger: + """ + Args: + Context manager to capture `logging` streams + logger: 'logging` logger object + Returns: + The captured output is available via `self.out` + Example: + ```python + >>> from diffusers import logging + >>> from diffusers.testing_utils import CaptureLogger + + >>> msg = "Testing 1, 2, 3" + >>> logging.set_verbosity_info() + >>> logger = logging.get_logger("diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion.py") + >>> with CaptureLogger(logger) as cl: + ... logger.info(msg) + >>> assert cl.out, msg + "\n" + ``` + """ + + def __init__(self, logger): + self.logger = logger + self.io = StringIO() + self.sh = logging.StreamHandler(self.io) + self.out = "" + + def __enter__(self): + self.logger.addHandler(self.sh) + return self + + def __exit__(self, *exc): + self.logger.removeHandler(self.sh) + self.out = self.io.getvalue() + + def __repr__(self): + return f"captured: {self.out}\n" + + +def enable_full_determinism(): + """ + Helper function for reproducible behavior during distributed training. See + - https://pytorch.org/docs/stable/notes/randomness.html for pytorch + """ + # Enable PyTorch deterministic mode. This potentially requires either the environment + # variable 'CUDA_LAUNCH_BLOCKING' or 'CUBLAS_WORKSPACE_CONFIG' to be set, + # depending on the CUDA version, so we set them both here + os.environ["CUDA_LAUNCH_BLOCKING"] = "1" + os.environ["CUBLAS_WORKSPACE_CONFIG"] = ":16:8" + torch.use_deterministic_algorithms(True) + + # Enable CUDNN deterministic mode + torch.backends.cudnn.deterministic = True + torch.backends.cudnn.benchmark = False + torch.backends.cuda.matmul.allow_tf32 = False + + +def disable_full_determinism(): + os.environ["CUDA_LAUNCH_BLOCKING"] = "0" + os.environ["CUBLAS_WORKSPACE_CONFIG"] = "" + torch.use_deterministic_algorithms(False) + + +# Utils for custom and alternative accelerator devices +def _is_torch_fp16_available(device): + if not is_torch_available(): + return False + + import torch + + device = torch.device(device) + + try: + x = torch.zeros((2, 2), dtype=torch.float16).to(device) + _ = torch.mul(x, x) + return True + + except Exception as e: + if device.type == "cuda": + raise ValueError( + f"You have passed a device of type 'cuda' which should work with 'fp16', but 'cuda' does not seem to be correctly installed on your machine: {e}" + ) + + return False + + +def _is_torch_fp64_available(device): + if not is_torch_available(): + return False + + import torch + + device = torch.device(device) + + try: + x = torch.zeros((2, 2), dtype=torch.float64).to(device) + _ = torch.mul(x, x) + return True + + except Exception as e: + if device.type == "cuda": + raise ValueError( + f"You have passed a device of type 'cuda' which should work with 'fp64', but 'cuda' does not seem to be correctly installed on your machine: {e}" + ) + + return False + + +# Guard these lookups for when Torch is not used - alternative accelerator support is for PyTorch +if is_torch_available(): + # Behaviour flags + BACKEND_SUPPORTS_TRAINING = {"cuda": True, "xpu": True, "cpu": True, "mps": False, "default": True} + + # Function definitions + BACKEND_EMPTY_CACHE = { + "cuda": torch.cuda.empty_cache, + "xpu": torch.xpu.empty_cache, + "cpu": None, + "mps": torch.mps.empty_cache, + "default": None, + } + BACKEND_DEVICE_COUNT = { + "cuda": torch.cuda.device_count, + "xpu": torch.xpu.device_count, + "cpu": lambda: 0, + "mps": lambda: 0, + "default": 0, + } + BACKEND_MANUAL_SEED = { + "cuda": torch.cuda.manual_seed, + "xpu": torch.xpu.manual_seed, + "cpu": torch.manual_seed, + "mps": torch.mps.manual_seed, + "default": torch.manual_seed, + } + BACKEND_RESET_PEAK_MEMORY_STATS = { + "cuda": torch.cuda.reset_peak_memory_stats, + "xpu": getattr(torch.xpu, "reset_peak_memory_stats", None), + "cpu": None, + "mps": None, + "default": None, + } + BACKEND_RESET_MAX_MEMORY_ALLOCATED = { + "cuda": torch.cuda.reset_max_memory_allocated, + "xpu": getattr(torch.xpu, "reset_peak_memory_stats", None), + "cpu": None, + "mps": None, + "default": None, + } + BACKEND_MAX_MEMORY_ALLOCATED = { + "cuda": torch.cuda.max_memory_allocated, + "xpu": getattr(torch.xpu, "max_memory_allocated", None), + "cpu": 0, + "mps": 0, + "default": 0, + } + BACKEND_SYNCHRONIZE = { + "cuda": torch.cuda.synchronize, + "xpu": getattr(torch.xpu, "synchronize", None), + "cpu": None, + "mps": None, + "default": None, + } + + +# This dispatches a defined function according to the accelerator from the function definitions. +def _device_agnostic_dispatch(device: str, dispatch_table: Dict[str, Callable], *args, **kwargs): + if device not in dispatch_table: + return dispatch_table["default"](*args, **kwargs) + + fn = dispatch_table[device] + + # Some device agnostic functions return values. Need to guard against 'None' instead at + # user level + if not callable(fn): + return fn + + return fn(*args, **kwargs) + + +# These are callables which automatically dispatch the function specific to the accelerator +def backend_manual_seed(device: str, seed: int): + return _device_agnostic_dispatch(device, BACKEND_MANUAL_SEED, seed) + + +def backend_synchronize(device: str): + return _device_agnostic_dispatch(device, BACKEND_SYNCHRONIZE) + + +def backend_empty_cache(device: str): + return _device_agnostic_dispatch(device, BACKEND_EMPTY_CACHE) + + +def backend_device_count(device: str): + return _device_agnostic_dispatch(device, BACKEND_DEVICE_COUNT) + + +def backend_reset_peak_memory_stats(device: str): + return _device_agnostic_dispatch(device, BACKEND_RESET_PEAK_MEMORY_STATS) + + +def backend_reset_max_memory_allocated(device: str): + return _device_agnostic_dispatch(device, BACKEND_RESET_MAX_MEMORY_ALLOCATED) + + +def backend_max_memory_allocated(device: str): + return _device_agnostic_dispatch(device, BACKEND_MAX_MEMORY_ALLOCATED) + + +# These are callables which return boolean behaviour flags and can be used to specify some +# device agnostic alternative where the feature is unsupported. +def backend_supports_training(device: str): + if not is_torch_available(): + return False + + if device not in BACKEND_SUPPORTS_TRAINING: + device = "default" + + return BACKEND_SUPPORTS_TRAINING[device] + + +# Guard for when Torch is not available +if is_torch_available(): + # Update device function dict mapping + def update_mapping_from_spec(device_fn_dict: Dict[str, Callable], attribute_name: str): + try: + # Try to import the function directly + spec_fn = getattr(device_spec_module, attribute_name) + device_fn_dict[torch_device] = spec_fn + except AttributeError as e: + # If the function doesn't exist, and there is no default, throw an error + if "default" not in device_fn_dict: + raise AttributeError( + f"`{attribute_name}` not found in '{device_spec_path}' and no default fallback function found." + ) from e + + if "DIFFUSERS_TEST_DEVICE_SPEC" in os.environ: + device_spec_path = os.environ["DIFFUSERS_TEST_DEVICE_SPEC"] + if not Path(device_spec_path).is_file(): + raise ValueError(f"Specified path to device specification file is not found. Received {device_spec_path}") + + try: + import_name = device_spec_path[: device_spec_path.index(".py")] + except ValueError as e: + raise ValueError(f"Provided device spec file is not a Python file! Received {device_spec_path}") from e + + device_spec_module = importlib.import_module(import_name) + + try: + device_name = device_spec_module.DEVICE_NAME + except AttributeError: + raise AttributeError("Device spec file did not contain `DEVICE_NAME`") + + if "DIFFUSERS_TEST_DEVICE" in os.environ and torch_device != device_name: + msg = f"Mismatch between environment variable `DIFFUSERS_TEST_DEVICE` '{torch_device}' and device found in spec '{device_name}'\n" + msg += "Either unset `DIFFUSERS_TEST_DEVICE` or ensure it matches device spec name." + raise ValueError(msg) + + torch_device = device_name + + # Add one entry here for each `BACKEND_*` dictionary. + update_mapping_from_spec(BACKEND_MANUAL_SEED, "MANUAL_SEED_FN") + update_mapping_from_spec(BACKEND_EMPTY_CACHE, "EMPTY_CACHE_FN") + update_mapping_from_spec(BACKEND_DEVICE_COUNT, "DEVICE_COUNT_FN") + update_mapping_from_spec(BACKEND_SUPPORTS_TRAINING, "SUPPORTS_TRAINING") + update_mapping_from_spec(BACKEND_RESET_PEAK_MEMORY_STATS, "RESET_PEAK_MEMORY_STATS_FN") + update_mapping_from_spec(BACKEND_RESET_MAX_MEMORY_ALLOCATED, "RESET_MAX_MEMORY_ALLOCATED_FN") + update_mapping_from_spec(BACKEND_MAX_MEMORY_ALLOCATED, "MAX_MEMORY_ALLOCATED_FN") + + +# Modified from https://github.com/huggingface/transformers/blob/cdfb018d0300fef3b07d9220f3efe9c2a9974662/src/transformers/testing_utils.py#L3090 + +# Type definition of key used in `Expectations` class. +DeviceProperties = Tuple[Union[str, None], Union[int, None]] + + +@functools.lru_cache +def get_device_properties() -> DeviceProperties: + """ + Get environment device properties. + """ + if IS_CUDA_SYSTEM or IS_ROCM_SYSTEM: + import torch + + major, _ = torch.cuda.get_device_capability() + if IS_ROCM_SYSTEM: + return ("rocm", major) + else: + return ("cuda", major) + elif IS_XPU_SYSTEM: + import torch + + # To get more info of the architecture meaning and bit allocation, refer to https://github.com/intel/llvm/blob/sycl/sycl/include/sycl/ext/oneapi/experimental/device_architecture.def + arch = torch.xpu.get_device_capability()["architecture"] + gen_mask = 0x000000FF00000000 + gen = (arch & gen_mask) >> 32 + return ("xpu", gen) + else: + return (torch_device, None) + + +if TYPE_CHECKING: + DevicePropertiesUserDict = UserDict[DeviceProperties, Any] +else: + DevicePropertiesUserDict = UserDict + + +class Expectations(DevicePropertiesUserDict): + def get_expectation(self) -> Any: + """ + Find best matching expectation based on environment device properties. + """ + return self.find_expectation(get_device_properties()) + + @staticmethod + def is_default(key: DeviceProperties) -> bool: + return all(p is None for p in key) + + @staticmethod + def score(key: DeviceProperties, other: DeviceProperties) -> int: + """ + Returns score indicating how similar two instances of the `Properties` tuple are. Points are calculated using + bits, but documented as int. Rules are as follows: + * Matching `type` gives 8 points. + * Semi-matching `type`, for example cuda and rocm, gives 4 points. + * Matching `major` (compute capability major version) gives 2 points. + * Default expectation (if present) gives 1 points. + """ + (device_type, major) = key + (other_device_type, other_major) = other + + score = 0b0 + if device_type == other_device_type: + score |= 0b1000 + elif device_type in ["cuda", "rocm"] and other_device_type in ["cuda", "rocm"]: + score |= 0b100 + + if major == other_major and other_major is not None: + score |= 0b10 + + if Expectations.is_default(other): + score |= 0b1 + + return int(score) + + def find_expectation(self, key: DeviceProperties = (None, None)) -> Any: + """ + Find best matching expectation based on provided device properties. + """ + (result_key, result) = max(self.data.items(), key=lambda x: Expectations.score(key, x[0])) + + if Expectations.score(key, result_key) == 0: + raise ValueError(f"No matching expectation found for {key}") + + return result + + def __repr__(self): + return f"{self.data}" diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/torch_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/torch_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..bb5674092d096c0dab60b23e618dcbc233a1f736 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/torch_utils.py @@ -0,0 +1,174 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +PyTorch utilities: Utilities related to PyTorch +""" + +from typing import List, Optional, Tuple, Union + +from . import logging +from .import_utils import is_torch_available, is_torch_npu_available, is_torch_version + + +if is_torch_available(): + import torch + from torch.fft import fftn, fftshift, ifftn, ifftshift + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + +try: + from torch._dynamo import allow_in_graph as maybe_allow_in_graph +except (ImportError, ModuleNotFoundError): + + def maybe_allow_in_graph(cls): + return cls + + +def randn_tensor( + shape: Union[Tuple, List], + generator: Optional[Union[List["torch.Generator"], "torch.Generator"]] = None, + device: Optional[Union[str, "torch.device"]] = None, + dtype: Optional["torch.dtype"] = None, + layout: Optional["torch.layout"] = None, +): + """A helper function to create random tensors on the desired `device` with the desired `dtype`. When + passing a list of generators, you can seed each batch size individually. If CPU generators are passed, the tensor + is always created on the CPU. + """ + # device on which tensor is created defaults to device + if isinstance(device, str): + device = torch.device(device) + rand_device = device + batch_size = shape[0] + + layout = layout or torch.strided + device = device or torch.device("cpu") + + if generator is not None: + gen_device_type = generator.device.type if not isinstance(generator, list) else generator[0].device.type + if gen_device_type != device.type and gen_device_type == "cpu": + rand_device = "cpu" + if device != "mps": + logger.info( + f"The passed generator was created on 'cpu' even though a tensor on {device} was expected." + f" Tensors will be created on 'cpu' and then moved to {device}. Note that one can probably" + f" slightly speed up this function by passing a generator that was created on the {device} device." + ) + elif gen_device_type != device.type and gen_device_type == "cuda": + raise ValueError(f"Cannot generate a {device} tensor from a generator of type {gen_device_type}.") + + # make sure generator list of length 1 is treated like a non-list + if isinstance(generator, list) and len(generator) == 1: + generator = generator[0] + + if isinstance(generator, list): + shape = (1,) + shape[1:] + latents = [ + torch.randn(shape, generator=generator[i], device=rand_device, dtype=dtype, layout=layout) + for i in range(batch_size) + ] + latents = torch.cat(latents, dim=0).to(device) + else: + latents = torch.randn(shape, generator=generator, device=rand_device, dtype=dtype, layout=layout).to(device) + + return latents + + +def is_compiled_module(module) -> bool: + """Check whether the module was compiled with torch.compile()""" + if is_torch_version("<", "2.0.0") or not hasattr(torch, "_dynamo"): + return False + return isinstance(module, torch._dynamo.eval_frame.OptimizedModule) + + +def fourier_filter(x_in: "torch.Tensor", threshold: int, scale: int) -> "torch.Tensor": + """Fourier filter as introduced in FreeU (https://huggingface.co/papers/2309.11497). + + This version of the method comes from here: + https://github.com/huggingface/diffusers/pull/5164#issuecomment-1732638706 + """ + x = x_in + B, C, H, W = x.shape + + # Non-power of 2 images must be float32 + if (W & (W - 1)) != 0 or (H & (H - 1)) != 0: + x = x.to(dtype=torch.float32) + # fftn does not support bfloat16 + elif x.dtype == torch.bfloat16: + x = x.to(dtype=torch.float32) + + # FFT + x_freq = fftn(x, dim=(-2, -1)) + x_freq = fftshift(x_freq, dim=(-2, -1)) + + B, C, H, W = x_freq.shape + mask = torch.ones((B, C, H, W), device=x.device) + + crow, ccol = H // 2, W // 2 + mask[..., crow - threshold : crow + threshold, ccol - threshold : ccol + threshold] = scale + x_freq = x_freq * mask + + # IFFT + x_freq = ifftshift(x_freq, dim=(-2, -1)) + x_filtered = ifftn(x_freq, dim=(-2, -1)).real + + return x_filtered.to(dtype=x_in.dtype) + + +def apply_freeu( + resolution_idx: int, hidden_states: "torch.Tensor", res_hidden_states: "torch.Tensor", **freeu_kwargs +) -> Tuple["torch.Tensor", "torch.Tensor"]: + """Applies the FreeU mechanism as introduced in https: + //arxiv.org/abs/2309.11497. Adapted from the official code repository: https://github.com/ChenyangSi/FreeU. + + Args: + resolution_idx (`int`): Integer denoting the UNet block where FreeU is being applied. + hidden_states (`torch.Tensor`): Inputs to the underlying block. + res_hidden_states (`torch.Tensor`): Features from the skip block corresponding to the underlying block. + s1 (`float`): Scaling factor for stage 1 to attenuate the contributions of the skip features. + s2 (`float`): Scaling factor for stage 2 to attenuate the contributions of the skip features. + b1 (`float`): Scaling factor for stage 1 to amplify the contributions of backbone features. + b2 (`float`): Scaling factor for stage 2 to amplify the contributions of backbone features. + """ + if resolution_idx == 0: + num_half_channels = hidden_states.shape[1] // 2 + hidden_states[:, :num_half_channels] = hidden_states[:, :num_half_channels] * freeu_kwargs["b1"] + res_hidden_states = fourier_filter(res_hidden_states, threshold=1, scale=freeu_kwargs["s1"]) + if resolution_idx == 1: + num_half_channels = hidden_states.shape[1] // 2 + hidden_states[:, :num_half_channels] = hidden_states[:, :num_half_channels] * freeu_kwargs["b2"] + res_hidden_states = fourier_filter(res_hidden_states, threshold=1, scale=freeu_kwargs["s2"]) + + return hidden_states, res_hidden_states + + +def get_torch_cuda_device_capability(): + if torch.cuda.is_available(): + device = torch.device("cuda") + compute_capability = torch.cuda.get_device_capability(device) + compute_capability = f"{compute_capability[0]}.{compute_capability[1]}" + return float(compute_capability) + else: + return None + + +def get_device(): + if torch.cuda.is_available(): + return "cuda" + elif is_torch_npu_available(): + return "npu" + elif hasattr(torch, "xpu") and torch.xpu.is_available(): + return "xpu" + else: + return "cpu" diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/typing_utils.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/typing_utils.py new file mode 100644 index 0000000000000000000000000000000000000000..2b5b1a4f5ab5510856bf453a7436f6deb9c61abe --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/typing_utils.py @@ -0,0 +1,91 @@ +# Copyright 2025 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Typing utilities: Utilities related to type checking and validation +""" + +from typing import Any, Dict, List, Set, Tuple, Type, Union, get_args, get_origin + + +def _is_valid_type(obj: Any, class_or_tuple: Union[Type, Tuple[Type, ...]]) -> bool: + """ + Checks if an object is an instance of any of the provided types. For collections, it checks if every element is of + the correct type as well. + """ + if not isinstance(class_or_tuple, tuple): + class_or_tuple = (class_or_tuple,) + + # Unpack unions + unpacked_class_or_tuple = [] + for t in class_or_tuple: + if get_origin(t) is Union: + unpacked_class_or_tuple.extend(get_args(t)) + else: + unpacked_class_or_tuple.append(t) + class_or_tuple = tuple(unpacked_class_or_tuple) + + if Any in class_or_tuple: + return True + + obj_type = type(obj) + # Classes with obj's type + class_or_tuple = {t for t in class_or_tuple if isinstance(obj, get_origin(t) or t)} + + # Singular types (e.g. int, ControlNet, ...) + # Untyped collections (e.g. List, but not List[int]) + elem_class_or_tuple = {get_args(t) for t in class_or_tuple} + if () in elem_class_or_tuple: + return True + # Typed lists or sets + elif obj_type in (list, set): + return any(all(_is_valid_type(x, t) for x in obj) for t in elem_class_or_tuple) + # Typed tuples + elif obj_type is tuple: + return any( + # Tuples with any length and single type (e.g. Tuple[int, ...]) + (len(t) == 2 and t[-1] is Ellipsis and all(_is_valid_type(x, t[0]) for x in obj)) + or + # Tuples with fixed length and any types (e.g. Tuple[int, str]) + (len(obj) == len(t) and all(_is_valid_type(x, tt) for x, tt in zip(obj, t))) + for t in elem_class_or_tuple + ) + # Typed dicts + elif obj_type is dict: + return any( + all(_is_valid_type(k, kt) and _is_valid_type(v, vt) for k, v in obj.items()) + for kt, vt in elem_class_or_tuple + ) + + else: + return False + + +def _get_detailed_type(obj: Any) -> Type: + """ + Gets a detailed type for an object, including nested types for collections. + """ + obj_type = type(obj) + + if obj_type in (list, set): + obj_origin_type = List if obj_type is list else Set + elems_type = Union[tuple({_get_detailed_type(x) for x in obj})] + return obj_origin_type[elems_type] + elif obj_type is tuple: + return Tuple[tuple(_get_detailed_type(x) for x in obj)] + elif obj_type is dict: + keys_type = Union[tuple({_get_detailed_type(k) for k in obj.keys()})] + values_type = Union[tuple({_get_detailed_type(k) for k in obj.values()})] + return Dict[keys_type, values_type] + else: + return obj_type diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/versions.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/versions.py new file mode 100644 index 0000000000000000000000000000000000000000..945a3977ce62a9a55307862193e4be6f12c3c17f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/utils/versions.py @@ -0,0 +1,117 @@ +# Copyright 2020 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Utilities for working with package versions +""" + +import importlib.metadata +import operator +import re +import sys +from typing import Optional + +from packaging import version + + +ops = { + "<": operator.lt, + "<=": operator.le, + "==": operator.eq, + "!=": operator.ne, + ">=": operator.ge, + ">": operator.gt, +} + + +def _compare_versions(op, got_ver, want_ver, requirement, pkg, hint): + if got_ver is None or want_ver is None: + raise ValueError( + f"Unable to compare versions for {requirement}: need={want_ver} found={got_ver}. This is unusual. Consider" + f" reinstalling {pkg}." + ) + if not ops[op](version.parse(got_ver), version.parse(want_ver)): + raise ImportError( + f"{requirement} is required for a normal functioning of this module, but found {pkg}=={got_ver}.{hint}" + ) + + +def require_version(requirement: str, hint: Optional[str] = None) -> None: + """ + Perform a runtime check of the dependency versions, using the exact same syntax used by pip. + + The installed module version comes from the *site-packages* dir via *importlib.metadata*. + + Args: + requirement (`str`): pip style definition, e.g., "tokenizers==0.9.4", "tqdm>=4.27", "numpy" + hint (`str`, *optional*): what suggestion to print in case of requirements not being met + + Example: + + ```python + require_version("pandas>1.1.2") + require_version("numpy>1.18.5", "this is important to have for whatever reason") + ```""" + + hint = f"\n{hint}" if hint is not None else "" + + # non-versioned check + if re.match(r"^[\w_\-\d]+$", requirement): + pkg, op, want_ver = requirement, None, None + else: + match = re.findall(r"^([^!=<>\s]+)([\s!=<>]{1,2}.+)", requirement) + if not match: + raise ValueError( + "requirement needs to be in the pip package format, .e.g., package_a==1.23, or package_b>=1.23, but" + f" got {requirement}" + ) + pkg, want_full = match[0] + want_range = want_full.split(",") # there could be multiple requirements + wanted = {} + for w in want_range: + match = re.findall(r"^([\s!=<>]{1,2})(.+)", w) + if not match: + raise ValueError( + "requirement needs to be in the pip package format, .e.g., package_a==1.23, or package_b>=1.23," + f" but got {requirement}" + ) + op, want_ver = match[0] + wanted[op] = want_ver + if op not in ops: + raise ValueError(f"{requirement}: need one of {list(ops.keys())}, but got {op}") + + # special case + if pkg == "python": + got_ver = ".".join([str(x) for x in sys.version_info[:3]]) + for op, want_ver in wanted.items(): + _compare_versions(op, got_ver, want_ver, requirement, pkg, hint) + return + + # check if any version is installed + try: + got_ver = importlib.metadata.version(pkg) + except importlib.metadata.PackageNotFoundError: + raise importlib.metadata.PackageNotFoundError( + f"The '{requirement}' distribution was not found and is required by this application. {hint}" + ) + + # check that the right version is installed if version number or a range was provided + if want_ver is not None: + for op, want_ver in wanted.items(): + _compare_versions(op, got_ver, want_ver, requirement, pkg, hint) + + +def require_version_core(requirement): + """require_version wrapper which emits a core-specific hint on failure""" + hint = "Try: pip install transformers -U or pip install -e '.[dev]' if you're working with git main" + return require_version(requirement, hint) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/video_processor.py b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/video_processor.py new file mode 100644 index 0000000000000000000000000000000000000000..5d0fdde8b48305c2613c0f16d522a8365a74c39e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/src/diffusers/video_processor.py @@ -0,0 +1,113 @@ +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import warnings +from typing import List, Optional, Union + +import numpy as np +import PIL +import torch + +from .image_processor import VaeImageProcessor, is_valid_image, is_valid_image_imagelist + + +class VideoProcessor(VaeImageProcessor): + r"""Simple video processor.""" + + def preprocess_video(self, video, height: Optional[int] = None, width: Optional[int] = None) -> torch.Tensor: + r""" + Preprocesses input video(s). + + Args: + video (`List[PIL.Image]`, `List[List[PIL.Image]]`, `torch.Tensor`, `np.array`, `List[torch.Tensor]`, `List[np.array]`): + The input video. It can be one of the following: + * List of the PIL images. + * List of list of PIL images. + * 4D Torch tensors (expected shape for each tensor `(num_frames, num_channels, height, width)`). + * 4D NumPy arrays (expected shape for each array `(num_frames, height, width, num_channels)`). + * List of 4D Torch tensors (expected shape for each tensor `(num_frames, num_channels, height, + width)`). + * List of 4D NumPy arrays (expected shape for each array `(num_frames, height, width, num_channels)`). + * 5D NumPy arrays: expected shape for each array `(batch_size, num_frames, height, width, + num_channels)`. + * 5D Torch tensors: expected shape for each array `(batch_size, num_frames, num_channels, height, + width)`. + height (`int`, *optional*, defaults to `None`): + The height in preprocessed frames of the video. If `None`, will use the `get_default_height_width()` to + get default height. + width (`int`, *optional*`, defaults to `None`): + The width in preprocessed frames of the video. If `None`, will use get_default_height_width()` to get + the default width. + """ + if isinstance(video, list) and isinstance(video[0], np.ndarray) and video[0].ndim == 5: + warnings.warn( + "Passing `video` as a list of 5d np.ndarray is deprecated." + "Please concatenate the list along the batch dimension and pass it as a single 5d np.ndarray", + FutureWarning, + ) + video = np.concatenate(video, axis=0) + if isinstance(video, list) and isinstance(video[0], torch.Tensor) and video[0].ndim == 5: + warnings.warn( + "Passing `video` as a list of 5d torch.Tensor is deprecated." + "Please concatenate the list along the batch dimension and pass it as a single 5d torch.Tensor", + FutureWarning, + ) + video = torch.cat(video, axis=0) + + # ensure the input is a list of videos: + # - if it is a batch of videos (5d torch.Tensor or np.ndarray), it is converted to a list of videos (a list of 4d torch.Tensor or np.ndarray) + # - if it is a single video, it is converted to a list of one video. + if isinstance(video, (np.ndarray, torch.Tensor)) and video.ndim == 5: + video = list(video) + elif isinstance(video, list) and is_valid_image(video[0]) or is_valid_image_imagelist(video): + video = [video] + elif isinstance(video, list) and is_valid_image_imagelist(video[0]): + video = video + else: + raise ValueError( + "Input is in incorrect format. Currently, we only support numpy.ndarray, torch.Tensor, PIL.Image.Image" + ) + + video = torch.stack([self.preprocess(img, height=height, width=width) for img in video], dim=0) + + # move the number of channels before the number of frames. + video = video.permute(0, 2, 1, 3, 4) + + return video + + def postprocess_video( + self, video: torch.Tensor, output_type: str = "np" + ) -> Union[np.ndarray, torch.Tensor, List[PIL.Image.Image]]: + r""" + Converts a video tensor to a list of frames for export. + + Args: + video (`torch.Tensor`): The video as a tensor. + output_type (`str`, defaults to `"np"`): Output type of the postprocessed `video` tensor. + """ + batch_size = video.shape[0] + outputs = [] + for batch_idx in range(batch_size): + batch_vid = video[batch_idx].permute(1, 0, 2, 3) + batch_output = self.postprocess(batch_vid, output_type) + outputs.append(batch_output) + + if output_type == "np": + outputs = np.stack(outputs) + elif output_type == "pt": + outputs = torch.stack(outputs) + elif not output_type == "pil": + raise ValueError(f"{output_type} does not exist. Please choose one of ['np', 'pt', 'pil']") + + return outputs diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_config_docstrings.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_config_docstrings.py new file mode 100644 index 0000000000000000000000000000000000000000..d39fe6a618d4d7e0476f32578a488aa3402abde6 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_config_docstrings.py @@ -0,0 +1,84 @@ +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import importlib +import inspect +import os +import re + + +# All paths are set with the intent you should run this script from the root of the repo with the command +# python utils/check_config_docstrings.py +PATH_TO_TRANSFORMERS = "src/transformers" + + +# This is to make sure the transformers module imported is the one in the repo. +spec = importlib.util.spec_from_file_location( + "transformers", + os.path.join(PATH_TO_TRANSFORMERS, "__init__.py"), + submodule_search_locations=[PATH_TO_TRANSFORMERS], +) +transformers = spec.loader.load_module() + +CONFIG_MAPPING = transformers.models.auto.configuration_auto.CONFIG_MAPPING + +# Regex pattern used to find the checkpoint mentioned in the docstring of `config_class`. +# For example, `[bert-base-uncased](https://huggingface.co/bert-base-uncased)` +_re_checkpoint = re.compile(r"\[(.+?)\]\((https://huggingface\.co/.+?)\)") + + +CONFIG_CLASSES_TO_IGNORE_FOR_DOCSTRING_CHECKPOINT_CHECK = { + "CLIPConfigMixin", + "DecisionTransformerConfigMixin", + "EncoderDecoderConfigMixin", + "RagConfigMixin", + "SpeechEncoderDecoderConfigMixin", + "VisionEncoderDecoderConfigMixin", + "VisionTextDualEncoderConfigMixin", +} + + +def check_config_docstrings_have_checkpoints(): + configs_without_checkpoint = [] + + for config_class in list(CONFIG_MAPPING.values()): + checkpoint_found = False + + # source code of `config_class` + config_source = inspect.getsource(config_class) + checkpoints = _re_checkpoint.findall(config_source) + + for checkpoint in checkpoints: + # Each `checkpoint` is a tuple of a checkpoint name and a checkpoint link. + # For example, `('bert-base-uncased', 'https://huggingface.co/bert-base-uncased')` + ckpt_name, ckpt_link = checkpoint + + # verify the checkpoint name corresponds to the checkpoint link + ckpt_link_from_name = f"https://huggingface.co/{ckpt_name}" + if ckpt_link == ckpt_link_from_name: + checkpoint_found = True + break + + name = config_class.__name__ + if not checkpoint_found and name not in CONFIG_CLASSES_TO_IGNORE_FOR_DOCSTRING_CHECKPOINT_CHECK: + configs_without_checkpoint.append(name) + + if len(configs_without_checkpoint) > 0: + message = "\n".join(sorted(configs_without_checkpoint)) + raise ValueError(f"The following configurations don't contain any valid checkpoint:\n{message}") + + +if __name__ == "__main__": + check_config_docstrings_have_checkpoints() diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_copies.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_copies.py new file mode 100644 index 0000000000000000000000000000000000000000..001366c1905f5fda8a8e22f38b532013657e8ee3 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_copies.py @@ -0,0 +1,222 @@ +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import argparse +import glob +import os +import re +import subprocess + + +# All paths are set with the intent you should run this script from the root of the repo with the command +# python utils/check_copies.py +DIFFUSERS_PATH = "src/diffusers" +REPO_PATH = "." + + +def _should_continue(line, indent): + return line.startswith(indent) or len(line) <= 1 or re.search(r"^\s*\)(\s*->.*:|:)\s*$", line) is not None + + +def find_code_in_diffusers(object_name): + """Find and return the code source code of `object_name`.""" + parts = object_name.split(".") + i = 0 + + # First let's find the module where our object lives. + module = parts[i] + while i < len(parts) and not os.path.isfile(os.path.join(DIFFUSERS_PATH, f"{module}.py")): + i += 1 + if i < len(parts): + module = os.path.join(module, parts[i]) + if i >= len(parts): + raise ValueError(f"`object_name` should begin with the name of a module of diffusers but got {object_name}.") + + with open( + os.path.join(DIFFUSERS_PATH, f"{module}.py"), + "r", + encoding="utf-8", + newline="\n", + ) as f: + lines = f.readlines() + + # Now let's find the class / func in the code! + indent = "" + line_index = 0 + for name in parts[i + 1 :]: + while ( + line_index < len(lines) and re.search(rf"^{indent}(class|def)\s+{name}(\(|\:)", lines[line_index]) is None + ): + line_index += 1 + indent += " " + line_index += 1 + + if line_index >= len(lines): + raise ValueError(f" {object_name} does not match any function or class in {module}.") + + # We found the beginning of the class / func, now let's find the end (when the indent diminishes). + start_index = line_index + while line_index < len(lines) and _should_continue(lines[line_index], indent): + line_index += 1 + # Clean up empty lines at the end (if any). + while len(lines[line_index - 1]) <= 1: + line_index -= 1 + + code_lines = lines[start_index:line_index] + return "".join(code_lines) + + +_re_copy_warning = re.compile(r"^(\s*)#\s*Copied from\s+diffusers\.(\S+\.\S+)\s*($|\S.*$)") +_re_replace_pattern = re.compile(r"^\s*(\S+)->(\S+)(\s+.*|$)") +_re_fill_pattern = re.compile(r"]*>") + + +def get_indent(code): + lines = code.split("\n") + idx = 0 + while idx < len(lines) and len(lines[idx]) == 0: + idx += 1 + if idx < len(lines): + return re.search(r"^(\s*)\S", lines[idx]).groups()[0] + return "" + + +def run_ruff(code): + command = ["ruff", "format", "-", "--config", "pyproject.toml", "--silent"] + process = subprocess.Popen(command, stdout=subprocess.PIPE, stderr=subprocess.PIPE, stdin=subprocess.PIPE) + stdout, _ = process.communicate(input=code.encode()) + return stdout.decode() + + +def stylify(code: str) -> str: + """ + Applies the ruff part of our `make style` command to some code. This formats the code using `ruff format`. + As `ruff` does not provide a python api this cannot be done on the fly. + + Args: + code (`str`): The code to format. + + Returns: + `str`: The formatted code. + """ + has_indent = len(get_indent(code)) > 0 + if has_indent: + code = f"class Bla:\n{code}" + formatted_code = run_ruff(code) + return formatted_code[len("class Bla:\n") :] if has_indent else formatted_code + + +def is_copy_consistent(filename, overwrite=False): + """ + Check if the code commented as a copy in `filename` matches the original. + Return the differences or overwrites the content depending on `overwrite`. + """ + with open(filename, "r", encoding="utf-8", newline="\n") as f: + lines = f.readlines() + diffs = [] + line_index = 0 + # Not a for loop cause `lines` is going to change (if `overwrite=True`). + while line_index < len(lines): + search = _re_copy_warning.search(lines[line_index]) + if search is None: + line_index += 1 + continue + + # There is some copied code here, let's retrieve the original. + indent, object_name, replace_pattern = search.groups() + theoretical_code = find_code_in_diffusers(object_name) + theoretical_indent = get_indent(theoretical_code) + + start_index = line_index + 1 if indent == theoretical_indent else line_index + 2 + indent = theoretical_indent + line_index = start_index + + # Loop to check the observed code, stop when indentation diminishes or if we see a End copy comment. + should_continue = True + while line_index < len(lines) and should_continue: + line_index += 1 + if line_index >= len(lines): + break + line = lines[line_index] + should_continue = _should_continue(line, indent) and re.search(f"^{indent}# End copy", line) is None + # Clean up empty lines at the end (if any). + while len(lines[line_index - 1]) <= 1: + line_index -= 1 + + observed_code_lines = lines[start_index:line_index] + observed_code = "".join(observed_code_lines) + + # Remove any nested `Copied from` comments to avoid circular copies + theoretical_code = [line for line in theoretical_code.split("\n") if _re_copy_warning.search(line) is None] + theoretical_code = "\n".join(theoretical_code) + + # Before comparing, use the `replace_pattern` on the original code. + if len(replace_pattern) > 0: + patterns = replace_pattern.replace("with", "").split(",") + patterns = [_re_replace_pattern.search(p) for p in patterns] + for pattern in patterns: + if pattern is None: + continue + obj1, obj2, option = pattern.groups() + theoretical_code = re.sub(obj1, obj2, theoretical_code) + if option.strip() == "all-casing": + theoretical_code = re.sub(obj1.lower(), obj2.lower(), theoretical_code) + theoretical_code = re.sub(obj1.upper(), obj2.upper(), theoretical_code) + + # stylify after replacement. To be able to do that, we need the header (class or function definition) + # from the previous line + theoretical_code = stylify(lines[start_index - 1] + theoretical_code) + theoretical_code = theoretical_code[len(lines[start_index - 1]) :] + + # Test for a diff and act accordingly. + if observed_code != theoretical_code: + diffs.append([object_name, start_index]) + if overwrite: + lines = lines[:start_index] + [theoretical_code] + lines[line_index:] + line_index = start_index + 1 + + if overwrite and len(diffs) > 0: + # Warn the user a file has been modified. + print(f"Detected changes, rewriting {filename}.") + with open(filename, "w", encoding="utf-8", newline="\n") as f: + f.writelines(lines) + return diffs + + +def check_copies(overwrite: bool = False): + all_files = glob.glob(os.path.join(DIFFUSERS_PATH, "**/*.py"), recursive=True) + diffs = [] + for filename in all_files: + new_diffs = is_copy_consistent(filename, overwrite) + diffs += [f"- {filename}: copy does not match {d[0]} at line {d[1]}" for d in new_diffs] + if not overwrite and len(diffs) > 0: + diff = "\n".join(diffs) + raise Exception( + "Found the following copy inconsistencies:\n" + + diff + + "\nRun `make fix-copies` or `python utils/check_copies.py --fix_and_overwrite` to fix them." + ) + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument( + "--fix_and_overwrite", + action="store_true", + help="Whether to fix inconsistencies.", + ) + args = parser.parse_args() + + check_copies(args.fix_and_overwrite) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_doc_toc.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_doc_toc.py new file mode 100644 index 0000000000000000000000000000000000000000..0dd02cde86c1286c7fb2cc00d469d31714ce3a09 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_doc_toc.py @@ -0,0 +1,210 @@ +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import argparse +from collections import defaultdict + +import yaml + + +PATH_TO_TOC = "docs/source/en/_toctree.yml" + + +def clean_doc_toc(doc_list): + """ + Cleans the table of content of the model documentation by removing duplicates and sorting models alphabetically. + """ + counts = defaultdict(int) + overview_doc = [] + new_doc_list = [] + for doc in doc_list: + if "local" in doc: + counts[doc["local"]] += 1 + + if doc["title"].lower() == "overview": + overview_doc.append({"local": doc["local"], "title": doc["title"]}) + else: + new_doc_list.append(doc) + + doc_list = new_doc_list + duplicates = [key for key, value in counts.items() if value > 1] + + new_doc = [] + for duplicate_key in duplicates: + titles = list({doc["title"] for doc in doc_list if doc["local"] == duplicate_key}) + if len(titles) > 1: + raise ValueError( + f"{duplicate_key} is present several times in the documentation table of content at " + "`docs/source/en/_toctree.yml` with different *Title* values. Choose one of those and remove the " + "others." + ) + # Only add this once + new_doc.append({"local": duplicate_key, "title": titles[0]}) + + # Add none duplicate-keys + new_doc.extend([doc for doc in doc_list if "local" not in counts or counts[doc["local"]] == 1]) + new_doc = sorted(new_doc, key=lambda s: s["title"].lower()) + + # "overview" gets special treatment and is always first + if len(overview_doc) > 1: + raise ValueError("{doc_list} has two 'overview' docs which is not allowed.") + + overview_doc.extend(new_doc) + + # Sort + return overview_doc + + +def check_scheduler_doc(overwrite=False): + with open(PATH_TO_TOC, encoding="utf-8") as f: + content = yaml.safe_load(f.read()) + + # Get to the API doc + api_idx = 0 + while content[api_idx]["title"] != "API": + api_idx += 1 + api_doc = content[api_idx]["sections"] + + # Then to the model doc + scheduler_idx = 0 + while api_doc[scheduler_idx]["title"] != "Schedulers": + scheduler_idx += 1 + + scheduler_doc = api_doc[scheduler_idx]["sections"] + new_scheduler_doc = clean_doc_toc(scheduler_doc) + + diff = False + if new_scheduler_doc != scheduler_doc: + diff = True + if overwrite: + api_doc[scheduler_idx]["sections"] = new_scheduler_doc + + if diff: + if overwrite: + content[api_idx]["sections"] = api_doc + with open(PATH_TO_TOC, "w", encoding="utf-8") as f: + f.write(yaml.dump(content, allow_unicode=True)) + else: + raise ValueError( + "The model doc part of the table of content is not properly sorted, run `make style` to fix this." + ) + + +def check_pipeline_doc(overwrite=False): + with open(PATH_TO_TOC, encoding="utf-8") as f: + content = yaml.safe_load(f.read()) + + # Get to the API doc + api_idx = 0 + while content[api_idx]["title"] != "API": + api_idx += 1 + api_doc = content[api_idx]["sections"] + + # Then to the model doc + pipeline_idx = 0 + while api_doc[pipeline_idx]["title"] != "Pipelines": + pipeline_idx += 1 + + diff = False + pipeline_docs = api_doc[pipeline_idx]["sections"] + new_pipeline_docs = [] + + # sort sub pipeline docs + for pipeline_doc in pipeline_docs: + if "sections" in pipeline_doc: + sub_pipeline_doc = pipeline_doc["sections"] + new_sub_pipeline_doc = clean_doc_toc(sub_pipeline_doc) + if new_sub_pipeline_doc != sub_pipeline_doc: + diff = True + if overwrite: + pipeline_doc["sections"] = new_sub_pipeline_doc + new_pipeline_docs.append(pipeline_doc) + + # sort overall pipeline doc + new_pipeline_docs = clean_doc_toc(new_pipeline_docs) + + if new_pipeline_docs != pipeline_docs: + diff = True + if overwrite: + api_doc[pipeline_idx]["sections"] = new_pipeline_docs + + if diff: + if overwrite: + content[api_idx]["sections"] = api_doc + with open(PATH_TO_TOC, "w", encoding="utf-8") as f: + f.write(yaml.dump(content, allow_unicode=True)) + else: + raise ValueError( + "The model doc part of the table of content is not properly sorted, run `make style` to fix this." + ) + + +def check_model_doc(overwrite=False): + with open(PATH_TO_TOC, encoding="utf-8") as f: + content = yaml.safe_load(f.read()) + + # Get to the API doc + api_idx = 0 + while content[api_idx]["title"] != "API": + api_idx += 1 + api_doc = content[api_idx]["sections"] + + # Then to the model doc + model_idx = 0 + while api_doc[model_idx]["title"] != "Models": + model_idx += 1 + + diff = False + model_docs = api_doc[model_idx]["sections"] + new_model_docs = [] + + # sort sub model docs + for model_doc in model_docs: + if "sections" in model_doc: + sub_model_doc = model_doc["sections"] + new_sub_model_doc = clean_doc_toc(sub_model_doc) + if new_sub_model_doc != sub_model_doc: + diff = True + if overwrite: + model_doc["sections"] = new_sub_model_doc + new_model_docs.append(model_doc) + + # sort overall model doc + new_model_docs = clean_doc_toc(new_model_docs) + + if new_model_docs != model_docs: + diff = True + if overwrite: + api_doc[model_idx]["sections"] = new_model_docs + + if diff: + if overwrite: + content[api_idx]["sections"] = api_doc + with open(PATH_TO_TOC, "w", encoding="utf-8") as f: + f.write(yaml.dump(content, allow_unicode=True)) + else: + raise ValueError( + "The model doc part of the table of content is not properly sorted, run `make style` to fix this." + ) + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument("--fix_and_overwrite", action="store_true", help="Whether to fix inconsistencies.") + args = parser.parse_args() + + check_scheduler_doc(args.fix_and_overwrite) + check_pipeline_doc(args.fix_and_overwrite) + check_model_doc(args.fix_and_overwrite) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_dummies.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_dummies.py new file mode 100644 index 0000000000000000000000000000000000000000..04a670c2f5d91c76b32b2c6d200b342675df6bb0 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_dummies.py @@ -0,0 +1,175 @@ +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import argparse +import os +import re + + +# All paths are set with the intent you should run this script from the root of the repo with the command +# python utils/check_dummies.py +PATH_TO_DIFFUSERS = "src/diffusers" + +# Matches is_xxx_available() +_re_backend = re.compile(r"is\_([a-z_]*)_available\(\)") +# Matches from xxx import bla +_re_single_line_import = re.compile(r"\s+from\s+\S*\s+import\s+([^\(\s].*)\n") + + +DUMMY_CONSTANT = """ +{0} = None +""" + +DUMMY_CLASS = """ +class {0}(metaclass=DummyObject): + _backends = {1} + + def __init__(self, *args, **kwargs): + requires_backends(self, {1}) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, {1}) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, {1}) +""" + + +DUMMY_FUNCTION = """ +def {0}(*args, **kwargs): + requires_backends({0}, {1}) +""" + + +def find_backend(line): + """Find one (or multiple) backend in a code line of the init.""" + backends = _re_backend.findall(line) + if len(backends) == 0: + return None + + return "_and_".join(backends) + + +def read_init(): + """Read the init and extracts PyTorch, TensorFlow, SentencePiece and Tokenizers objects.""" + with open(os.path.join(PATH_TO_DIFFUSERS, "__init__.py"), "r", encoding="utf-8", newline="\n") as f: + lines = f.readlines() + + # Get to the point we do the actual imports for type checking + line_index = 0 + while not lines[line_index].startswith("if TYPE_CHECKING"): + line_index += 1 + + backend_specific_objects = {} + # Go through the end of the file + while line_index < len(lines): + # If the line contains is_backend_available, we grab all objects associated with the `else` block + backend = find_backend(lines[line_index]) + if backend is not None: + while not lines[line_index].startswith(" else:"): + line_index += 1 + line_index += 1 + objects = [] + # Until we unindent, add backend objects to the list + while len(lines[line_index]) <= 1 or lines[line_index].startswith(" " * 8): + line = lines[line_index] + single_line_import_search = _re_single_line_import.search(line) + if single_line_import_search is not None: + objects.extend(single_line_import_search.groups()[0].split(", ")) + elif line.startswith(" " * 12): + objects.append(line[12:-2]) + line_index += 1 + + if len(objects) > 0: + backend_specific_objects[backend] = objects + else: + line_index += 1 + + return backend_specific_objects + + +def create_dummy_object(name, backend_name): + """Create the code for the dummy object corresponding to `name`.""" + if name.isupper(): + return DUMMY_CONSTANT.format(name) + elif name.islower(): + return DUMMY_FUNCTION.format(name, backend_name) + else: + return DUMMY_CLASS.format(name, backend_name) + + +def create_dummy_files(backend_specific_objects=None): + """Create the content of the dummy files.""" + if backend_specific_objects is None: + backend_specific_objects = read_init() + # For special correspondence backend to module name as used in the function requires_modulename + dummy_files = {} + + for backend, objects in backend_specific_objects.items(): + backend_name = "[" + ", ".join(f'"{b}"' for b in backend.split("_and_")) + "]" + dummy_file = "# This file is autogenerated by the command `make fix-copies`, do not edit.\n" + dummy_file += "from ..utils import DummyObject, requires_backends\n\n" + dummy_file += "\n".join([create_dummy_object(o, backend_name) for o in objects]) + dummy_files[backend] = dummy_file + + return dummy_files + + +def check_dummies(overwrite=False): + """Check if the dummy files are up to date and maybe `overwrite` with the right content.""" + dummy_files = create_dummy_files() + # For special correspondence backend to shortcut as used in utils/dummy_xxx_objects.py + short_names = {"torch": "pt"} + + # Locate actual dummy modules and read their content. + path = os.path.join(PATH_TO_DIFFUSERS, "utils") + dummy_file_paths = { + backend: os.path.join(path, f"dummy_{short_names.get(backend, backend)}_objects.py") + for backend in dummy_files.keys() + } + + actual_dummies = {} + for backend, file_path in dummy_file_paths.items(): + if os.path.isfile(file_path): + with open(file_path, "r", encoding="utf-8", newline="\n") as f: + actual_dummies[backend] = f.read() + else: + actual_dummies[backend] = "" + + for backend in dummy_files.keys(): + if dummy_files[backend] != actual_dummies[backend]: + if overwrite: + print( + f"Updating diffusers.utils.dummy_{short_names.get(backend, backend)}_objects.py as the main " + "__init__ has new objects." + ) + with open(dummy_file_paths[backend], "w", encoding="utf-8", newline="\n") as f: + f.write(dummy_files[backend]) + else: + raise ValueError( + "The main __init__ has objects that are not present in " + f"diffusers.utils.dummy_{short_names.get(backend, backend)}_objects.py. Run `make fix-copies` " + "to fix this." + ) + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument("--fix_and_overwrite", action="store_true", help="Whether to fix inconsistencies.") + args = parser.parse_args() + + check_dummies(args.fix_and_overwrite) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_inits.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_inits.py new file mode 100644 index 0000000000000000000000000000000000000000..8208fa634186536767054e8fb5f0d6f81bee7ba0 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_inits.py @@ -0,0 +1,299 @@ +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import collections +import importlib.util +import os +import re +from pathlib import Path + + +PATH_TO_TRANSFORMERS = "src/transformers" + + +# Matches is_xxx_available() +_re_backend = re.compile(r"is\_([a-z_]*)_available()") +# Catches a one-line _import_struct = {xxx} +_re_one_line_import_struct = re.compile(r"^_import_structure\s+=\s+\{([^\}]+)\}") +# Catches a line with a key-values pattern: "bla": ["foo", "bar"] +_re_import_struct_key_value = re.compile(r'\s+"\S*":\s+\[([^\]]*)\]') +# Catches a line if not is_foo_available +_re_test_backend = re.compile(r"^\s*if\s+not\s+is\_[a-z_]*\_available\(\)") +# Catches a line _import_struct["bla"].append("foo") +_re_import_struct_add_one = re.compile(r'^\s*_import_structure\["\S*"\]\.append\("(\S*)"\)') +# Catches a line _import_struct["bla"].extend(["foo", "bar"]) or _import_struct["bla"] = ["foo", "bar"] +_re_import_struct_add_many = re.compile(r"^\s*_import_structure\[\S*\](?:\.extend\(|\s*=\s+)\[([^\]]*)\]") +# Catches a line with an object between quotes and a comma: "MyModel", +_re_quote_object = re.compile(r'^\s+"([^"]+)",') +# Catches a line with objects between brackets only: ["foo", "bar"], +_re_between_brackets = re.compile(r"^\s+\[([^\]]+)\]") +# Catches a line with from foo import bar, bla, boo +_re_import = re.compile(r"\s+from\s+\S*\s+import\s+([^\(\s].*)\n") +# Catches a line with try: +_re_try = re.compile(r"^\s*try:") +# Catches a line with else: +_re_else = re.compile(r"^\s*else:") + + +def find_backend(line): + """Find one (or multiple) backend in a code line of the init.""" + if _re_test_backend.search(line) is None: + return None + backends = [b[0] for b in _re_backend.findall(line)] + backends.sort() + return "_and_".join(backends) + + +def parse_init(init_file): + """ + Read an init_file and parse (per backend) the _import_structure objects defined and the TYPE_CHECKING objects + defined + """ + with open(init_file, "r", encoding="utf-8", newline="\n") as f: + lines = f.readlines() + + line_index = 0 + while line_index < len(lines) and not lines[line_index].startswith("_import_structure = {"): + line_index += 1 + + # If this is a traditional init, just return. + if line_index >= len(lines): + return None + + # First grab the objects without a specific backend in _import_structure + objects = [] + while not lines[line_index].startswith("if TYPE_CHECKING") and find_backend(lines[line_index]) is None: + line = lines[line_index] + # If we have everything on a single line, let's deal with it. + if _re_one_line_import_struct.search(line): + content = _re_one_line_import_struct.search(line).groups()[0] + imports = re.findall(r"\[([^\]]+)\]", content) + for imp in imports: + objects.extend([obj[1:-1] for obj in imp.split(", ")]) + line_index += 1 + continue + single_line_import_search = _re_import_struct_key_value.search(line) + if single_line_import_search is not None: + imports = [obj[1:-1] for obj in single_line_import_search.groups()[0].split(", ") if len(obj) > 0] + objects.extend(imports) + elif line.startswith(" " * 8 + '"'): + objects.append(line[9:-3]) + line_index += 1 + + import_dict_objects = {"none": objects} + # Let's continue with backend-specific objects in _import_structure + while not lines[line_index].startswith("if TYPE_CHECKING"): + # If the line is an if not is_backend_available, we grab all objects associated. + backend = find_backend(lines[line_index]) + # Check if the backend declaration is inside a try block: + if _re_try.search(lines[line_index - 1]) is None: + backend = None + + if backend is not None: + line_index += 1 + + # Scroll until we hit the else block of try-except-else + while _re_else.search(lines[line_index]) is None: + line_index += 1 + + line_index += 1 + + objects = [] + # Until we unindent, add backend objects to the list + while len(lines[line_index]) <= 1 or lines[line_index].startswith(" " * 4): + line = lines[line_index] + if _re_import_struct_add_one.search(line) is not None: + objects.append(_re_import_struct_add_one.search(line).groups()[0]) + elif _re_import_struct_add_many.search(line) is not None: + imports = _re_import_struct_add_many.search(line).groups()[0].split(", ") + imports = [obj[1:-1] for obj in imports if len(obj) > 0] + objects.extend(imports) + elif _re_between_brackets.search(line) is not None: + imports = _re_between_brackets.search(line).groups()[0].split(", ") + imports = [obj[1:-1] for obj in imports if len(obj) > 0] + objects.extend(imports) + elif _re_quote_object.search(line) is not None: + objects.append(_re_quote_object.search(line).groups()[0]) + elif line.startswith(" " * 8 + '"'): + objects.append(line[9:-3]) + elif line.startswith(" " * 12 + '"'): + objects.append(line[13:-3]) + line_index += 1 + + import_dict_objects[backend] = objects + else: + line_index += 1 + + # At this stage we are in the TYPE_CHECKING part, first grab the objects without a specific backend + objects = [] + while ( + line_index < len(lines) + and find_backend(lines[line_index]) is None + and not lines[line_index].startswith("else") + ): + line = lines[line_index] + single_line_import_search = _re_import.search(line) + if single_line_import_search is not None: + objects.extend(single_line_import_search.groups()[0].split(", ")) + elif line.startswith(" " * 8): + objects.append(line[8:-2]) + line_index += 1 + + type_hint_objects = {"none": objects} + # Let's continue with backend-specific objects + while line_index < len(lines): + # If the line is an if is_backend_available, we grab all objects associated. + backend = find_backend(lines[line_index]) + # Check if the backend declaration is inside a try block: + if _re_try.search(lines[line_index - 1]) is None: + backend = None + + if backend is not None: + line_index += 1 + + # Scroll until we hit the else block of try-except-else + while _re_else.search(lines[line_index]) is None: + line_index += 1 + + line_index += 1 + + objects = [] + # Until we unindent, add backend objects to the list + while len(lines[line_index]) <= 1 or lines[line_index].startswith(" " * 8): + line = lines[line_index] + single_line_import_search = _re_import.search(line) + if single_line_import_search is not None: + objects.extend(single_line_import_search.groups()[0].split(", ")) + elif line.startswith(" " * 12): + objects.append(line[12:-2]) + line_index += 1 + + type_hint_objects[backend] = objects + else: + line_index += 1 + + return import_dict_objects, type_hint_objects + + +def analyze_results(import_dict_objects, type_hint_objects): + """ + Analyze the differences between _import_structure objects and TYPE_CHECKING objects found in an init. + """ + + def find_duplicates(seq): + return [k for k, v in collections.Counter(seq).items() if v > 1] + + if list(import_dict_objects.keys()) != list(type_hint_objects.keys()): + return ["Both sides of the init do not have the same backends!"] + + errors = [] + for key in import_dict_objects.keys(): + duplicate_imports = find_duplicates(import_dict_objects[key]) + if duplicate_imports: + errors.append(f"Duplicate _import_structure definitions for: {duplicate_imports}") + duplicate_type_hints = find_duplicates(type_hint_objects[key]) + if duplicate_type_hints: + errors.append(f"Duplicate TYPE_CHECKING objects for: {duplicate_type_hints}") + + if sorted(set(import_dict_objects[key])) != sorted(set(type_hint_objects[key])): + name = "base imports" if key == "none" else f"{key} backend" + errors.append(f"Differences for {name}:") + for a in type_hint_objects[key]: + if a not in import_dict_objects[key]: + errors.append(f" {a} in TYPE_HINT but not in _import_structure.") + for a in import_dict_objects[key]: + if a not in type_hint_objects[key]: + errors.append(f" {a} in _import_structure but not in TYPE_HINT.") + return errors + + +def check_all_inits(): + """ + Check all inits in the transformers repo and raise an error if at least one does not define the same objects in + both halves. + """ + failures = [] + for root, _, files in os.walk(PATH_TO_TRANSFORMERS): + if "__init__.py" in files: + fname = os.path.join(root, "__init__.py") + objects = parse_init(fname) + if objects is not None: + errors = analyze_results(*objects) + if len(errors) > 0: + errors[0] = f"Problem in {fname}, both halves do not define the same objects.\n{errors[0]}" + failures.append("\n".join(errors)) + if len(failures) > 0: + raise ValueError("\n\n".join(failures)) + + +def get_transformers_submodules(): + """ + Returns the list of Transformers submodules. + """ + submodules = [] + for path, directories, files in os.walk(PATH_TO_TRANSFORMERS): + for folder in directories: + # Ignore private modules + if folder.startswith("_"): + directories.remove(folder) + continue + # Ignore leftovers from branches (empty folders apart from pycache) + if len(list((Path(path) / folder).glob("*.py"))) == 0: + continue + short_path = str((Path(path) / folder).relative_to(PATH_TO_TRANSFORMERS)) + submodule = short_path.replace(os.path.sep, ".") + submodules.append(submodule) + for fname in files: + if fname == "__init__.py": + continue + short_path = str((Path(path) / fname).relative_to(PATH_TO_TRANSFORMERS)) + submodule = short_path.replace(".py", "").replace(os.path.sep, ".") + if len(submodule.split(".")) == 1: + submodules.append(submodule) + return submodules + + +IGNORE_SUBMODULES = [ + "convert_pytorch_checkpoint_to_tf2", + "modeling_flax_pytorch_utils", +] + + +def check_submodules(): + # This is to make sure the transformers module imported is the one in the repo. + spec = importlib.util.spec_from_file_location( + "transformers", + os.path.join(PATH_TO_TRANSFORMERS, "__init__.py"), + submodule_search_locations=[PATH_TO_TRANSFORMERS], + ) + transformers = spec.loader.load_module() + + module_not_registered = [ + module + for module in get_transformers_submodules() + if module not in IGNORE_SUBMODULES and module not in transformers._import_structure.keys() + ] + if len(module_not_registered) > 0: + list_of_modules = "\n".join(f"- {module}" for module in module_not_registered) + raise ValueError( + "The following submodules are not properly registered in the main init of Transformers:\n" + f"{list_of_modules}\n" + "Make sure they appear somewhere in the keys of `_import_structure` with an empty list as value." + ) + + +if __name__ == "__main__": + check_all_inits() + check_submodules() diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_repo.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_repo.py new file mode 100644 index 0000000000000000000000000000000000000000..14bdbe60adf06e4b6a3f79378f68393cc083b6a3 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_repo.py @@ -0,0 +1,755 @@ +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import importlib +import inspect +import os +import re +import warnings +from collections import OrderedDict +from difflib import get_close_matches +from pathlib import Path + +from diffusers.models.auto import get_values +from diffusers.utils import ENV_VARS_TRUE_VALUES, is_flax_available, is_torch_available + + +# All paths are set with the intent you should run this script from the root of the repo with the command +# python utils/check_repo.py +PATH_TO_DIFFUSERS = "src/diffusers" +PATH_TO_TESTS = "tests" +PATH_TO_DOC = "docs/source/en" + +# Update this list with models that are supposed to be private. +PRIVATE_MODELS = [ + "DPRSpanPredictor", + "RealmBertModel", + "T5Stack", + "TFDPRSpanPredictor", +] + +# Update this list for models that are not tested with a comment explaining the reason it should not be. +# Being in this list is an exception and should **not** be the rule. +IGNORE_NON_TESTED = PRIVATE_MODELS.copy() + [ + # models to ignore for not tested + "OPTDecoder", # Building part of bigger (tested) model. + "DecisionTransformerGPT2Model", # Building part of bigger (tested) model. + "SegformerDecodeHead", # Building part of bigger (tested) model. + "PLBartEncoder", # Building part of bigger (tested) model. + "PLBartDecoder", # Building part of bigger (tested) model. + "PLBartDecoderWrapper", # Building part of bigger (tested) model. + "BigBirdPegasusEncoder", # Building part of bigger (tested) model. + "BigBirdPegasusDecoder", # Building part of bigger (tested) model. + "BigBirdPegasusDecoderWrapper", # Building part of bigger (tested) model. + "DetrEncoder", # Building part of bigger (tested) model. + "DetrDecoder", # Building part of bigger (tested) model. + "DetrDecoderWrapper", # Building part of bigger (tested) model. + "M2M100Encoder", # Building part of bigger (tested) model. + "M2M100Decoder", # Building part of bigger (tested) model. + "Speech2TextEncoder", # Building part of bigger (tested) model. + "Speech2TextDecoder", # Building part of bigger (tested) model. + "LEDEncoder", # Building part of bigger (tested) model. + "LEDDecoder", # Building part of bigger (tested) model. + "BartDecoderWrapper", # Building part of bigger (tested) model. + "BartEncoder", # Building part of bigger (tested) model. + "BertLMHeadModel", # Needs to be setup as decoder. + "BlenderbotSmallEncoder", # Building part of bigger (tested) model. + "BlenderbotSmallDecoderWrapper", # Building part of bigger (tested) model. + "BlenderbotEncoder", # Building part of bigger (tested) model. + "BlenderbotDecoderWrapper", # Building part of bigger (tested) model. + "MBartEncoder", # Building part of bigger (tested) model. + "MBartDecoderWrapper", # Building part of bigger (tested) model. + "MegatronBertLMHeadModel", # Building part of bigger (tested) model. + "MegatronBertEncoder", # Building part of bigger (tested) model. + "MegatronBertDecoder", # Building part of bigger (tested) model. + "MegatronBertDecoderWrapper", # Building part of bigger (tested) model. + "PegasusEncoder", # Building part of bigger (tested) model. + "PegasusDecoderWrapper", # Building part of bigger (tested) model. + "DPREncoder", # Building part of bigger (tested) model. + "ProphetNetDecoderWrapper", # Building part of bigger (tested) model. + "RealmBertModel", # Building part of bigger (tested) model. + "RealmReader", # Not regular model. + "RealmScorer", # Not regular model. + "RealmForOpenQA", # Not regular model. + "ReformerForMaskedLM", # Needs to be setup as decoder. + "Speech2Text2DecoderWrapper", # Building part of bigger (tested) model. + "TFDPREncoder", # Building part of bigger (tested) model. + "TFElectraMainLayer", # Building part of bigger (tested) model (should it be a TFModelMixin ?) + "TFRobertaForMultipleChoice", # TODO: fix + "TrOCRDecoderWrapper", # Building part of bigger (tested) model. + "SeparableConv1D", # Building part of bigger (tested) model. + "FlaxBartForCausalLM", # Building part of bigger (tested) model. + "FlaxBertForCausalLM", # Building part of bigger (tested) model. Tested implicitly through FlaxRobertaForCausalLM. + "OPTDecoderWrapper", +] + +# Update this list with test files that don't have a tester with a `all_model_classes` variable and which don't +# trigger the common tests. +TEST_FILES_WITH_NO_COMMON_TESTS = [ + "models/decision_transformer/test_modeling_decision_transformer.py", + "models/camembert/test_modeling_camembert.py", + "models/mt5/test_modeling_flax_mt5.py", + "models/mbart/test_modeling_mbart.py", + "models/mt5/test_modeling_mt5.py", + "models/pegasus/test_modeling_pegasus.py", + "models/camembert/test_modeling_tf_camembert.py", + "models/mt5/test_modeling_tf_mt5.py", + "models/xlm_roberta/test_modeling_tf_xlm_roberta.py", + "models/xlm_roberta/test_modeling_flax_xlm_roberta.py", + "models/xlm_prophetnet/test_modeling_xlm_prophetnet.py", + "models/xlm_roberta/test_modeling_xlm_roberta.py", + "models/vision_text_dual_encoder/test_modeling_vision_text_dual_encoder.py", + "models/vision_text_dual_encoder/test_modeling_flax_vision_text_dual_encoder.py", + "models/decision_transformer/test_modeling_decision_transformer.py", +] + +# Update this list for models that are not in any of the auto MODEL_XXX_MAPPING. Being in this list is an exception and +# should **not** be the rule. +IGNORE_NON_AUTO_CONFIGURED = PRIVATE_MODELS.copy() + [ + # models to ignore for model xxx mapping + "DPTForDepthEstimation", + "DecisionTransformerGPT2Model", + "GLPNForDepthEstimation", + "ViltForQuestionAnswering", + "ViltForImagesAndTextClassification", + "ViltForImageAndTextRetrieval", + "ViltForMaskedLM", + "XGLMEncoder", + "XGLMDecoder", + "XGLMDecoderWrapper", + "PerceiverForMultimodalAutoencoding", + "PerceiverForOpticalFlow", + "SegformerDecodeHead", + "FlaxBeitForMaskedImageModeling", + "PLBartEncoder", + "PLBartDecoder", + "PLBartDecoderWrapper", + "BeitForMaskedImageModeling", + "CLIPTextModel", + "CLIPVisionModel", + "TFCLIPTextModel", + "TFCLIPVisionModel", + "FlaxCLIPTextModel", + "FlaxCLIPVisionModel", + "FlaxWav2Vec2ForCTC", + "DetrForSegmentation", + "DPRReader", + "FlaubertForQuestionAnswering", + "FlavaImageCodebook", + "FlavaTextModel", + "FlavaImageModel", + "FlavaMultimodalModel", + "GPT2DoubleHeadsModel", + "LukeForMaskedLM", + "LukeForEntityClassification", + "LukeForEntityPairClassification", + "LukeForEntitySpanClassification", + "OpenAIGPTDoubleHeadsModel", + "RagModel", + "RagSequenceForGeneration", + "RagTokenForGeneration", + "RealmEmbedder", + "RealmForOpenQA", + "RealmScorer", + "RealmReader", + "TFDPRReader", + "TFGPT2DoubleHeadsModel", + "TFOpenAIGPTDoubleHeadsModel", + "TFRagModel", + "TFRagSequenceForGeneration", + "TFRagTokenForGeneration", + "Wav2Vec2ForCTC", + "HubertForCTC", + "SEWForCTC", + "SEWDForCTC", + "XLMForQuestionAnswering", + "XLNetForQuestionAnswering", + "SeparableConv1D", + "VisualBertForRegionToPhraseAlignment", + "VisualBertForVisualReasoning", + "VisualBertForQuestionAnswering", + "VisualBertForMultipleChoice", + "TFWav2Vec2ForCTC", + "TFHubertForCTC", + "MaskFormerForInstanceSegmentation", +] + +# Update this list for models that have multiple model types for the same +# model doc +MODEL_TYPE_TO_DOC_MAPPING = OrderedDict( + [ + ("data2vec-text", "data2vec"), + ("data2vec-audio", "data2vec"), + ("data2vec-vision", "data2vec"), + ] +) + + +# This is to make sure the transformers module imported is the one in the repo. +spec = importlib.util.spec_from_file_location( + "diffusers", + os.path.join(PATH_TO_DIFFUSERS, "__init__.py"), + submodule_search_locations=[PATH_TO_DIFFUSERS], +) +diffusers = spec.loader.load_module() + + +def check_model_list(): + """Check the model list inside the transformers library.""" + # Get the models from the directory structure of `src/diffusers/models/` + models_dir = os.path.join(PATH_TO_DIFFUSERS, "models") + _models = [] + for model in os.listdir(models_dir): + model_dir = os.path.join(models_dir, model) + if os.path.isdir(model_dir) and "__init__.py" in os.listdir(model_dir): + _models.append(model) + + # Get the models from the directory structure of `src/transformers/models/` + models = [model for model in dir(diffusers.models) if not model.startswith("__")] + + missing_models = sorted(set(_models).difference(models)) + if missing_models: + raise Exception( + f"The following models should be included in {models_dir}/__init__.py: {','.join(missing_models)}." + ) + + +# If some modeling modules should be ignored for all checks, they should be added in the nested list +# _ignore_modules of this function. +def get_model_modules(): + """Get the model modules inside the transformers library.""" + _ignore_modules = [ + "modeling_auto", + "modeling_encoder_decoder", + "modeling_marian", + "modeling_mmbt", + "modeling_outputs", + "modeling_retribert", + "modeling_utils", + "modeling_flax_auto", + "modeling_flax_encoder_decoder", + "modeling_flax_utils", + "modeling_speech_encoder_decoder", + "modeling_flax_speech_encoder_decoder", + "modeling_flax_vision_encoder_decoder", + "modeling_transfo_xl_utilities", + "modeling_tf_auto", + "modeling_tf_encoder_decoder", + "modeling_tf_outputs", + "modeling_tf_pytorch_utils", + "modeling_tf_utils", + "modeling_tf_transfo_xl_utilities", + "modeling_tf_vision_encoder_decoder", + "modeling_vision_encoder_decoder", + ] + modules = [] + for model in dir(diffusers.models): + # There are some magic dunder attributes in the dir, we ignore them + if not model.startswith("__"): + model_module = getattr(diffusers.models, model) + for submodule in dir(model_module): + if submodule.startswith("modeling") and submodule not in _ignore_modules: + modeling_module = getattr(model_module, submodule) + if inspect.ismodule(modeling_module): + modules.append(modeling_module) + return modules + + +def get_models(module, include_pretrained=False): + """Get the objects in module that are models.""" + models = [] + model_classes = (diffusers.ModelMixin, diffusers.TFModelMixin, diffusers.FlaxModelMixin) + for attr_name in dir(module): + if not include_pretrained and ("Pretrained" in attr_name or "PreTrained" in attr_name): + continue + attr = getattr(module, attr_name) + if isinstance(attr, type) and issubclass(attr, model_classes) and attr.__module__ == module.__name__: + models.append((attr_name, attr)) + return models + + +def is_a_private_model(model): + """Returns True if the model should not be in the main init.""" + if model in PRIVATE_MODELS: + return True + + # Wrapper, Encoder and Decoder are all privates + if model.endswith("Wrapper"): + return True + if model.endswith("Encoder"): + return True + if model.endswith("Decoder"): + return True + return False + + +def check_models_are_in_init(): + """Checks all models defined in the library are in the main init.""" + models_not_in_init = [] + dir_transformers = dir(diffusers) + for module in get_model_modules(): + models_not_in_init += [ + model[0] for model in get_models(module, include_pretrained=True) if model[0] not in dir_transformers + ] + + # Remove private models + models_not_in_init = [model for model in models_not_in_init if not is_a_private_model(model)] + if len(models_not_in_init) > 0: + raise Exception(f"The following models should be in the main init: {','.join(models_not_in_init)}.") + + +# If some test_modeling files should be ignored when checking models are all tested, they should be added in the +# nested list _ignore_files of this function. +def get_model_test_files(): + """Get the model test files. + + The returned files should NOT contain the `tests` (i.e. `PATH_TO_TESTS` defined in this script). They will be + considered as paths relative to `tests`. A caller has to use `os.path.join(PATH_TO_TESTS, ...)` to access the files. + """ + + _ignore_files = [ + "test_modeling_common", + "test_modeling_encoder_decoder", + "test_modeling_flax_encoder_decoder", + "test_modeling_flax_speech_encoder_decoder", + "test_modeling_marian", + "test_modeling_tf_common", + "test_modeling_tf_encoder_decoder", + ] + test_files = [] + # Check both `PATH_TO_TESTS` and `PATH_TO_TESTS/models` + model_test_root = os.path.join(PATH_TO_TESTS, "models") + model_test_dirs = [] + for x in os.listdir(model_test_root): + x = os.path.join(model_test_root, x) + if os.path.isdir(x): + model_test_dirs.append(x) + + for target_dir in [PATH_TO_TESTS] + model_test_dirs: + for file_or_dir in os.listdir(target_dir): + path = os.path.join(target_dir, file_or_dir) + if os.path.isfile(path): + filename = os.path.split(path)[-1] + if "test_modeling" in filename and os.path.splitext(filename)[0] not in _ignore_files: + file = os.path.join(*path.split(os.sep)[1:]) + test_files.append(file) + + return test_files + + +# This is a bit hacky but I didn't find a way to import the test_file as a module and read inside the tester class +# for the all_model_classes variable. +def find_tested_models(test_file): + """Parse the content of test_file to detect what's in all_model_classes""" + # This is a bit hacky but I didn't find a way to import the test_file as a module and read inside the class + with open(os.path.join(PATH_TO_TESTS, test_file), "r", encoding="utf-8", newline="\n") as f: + content = f.read() + all_models = re.findall(r"all_model_classes\s+=\s+\(\s*\(([^\)]*)\)", content) + # Check with one less parenthesis as well + all_models += re.findall(r"all_model_classes\s+=\s+\(([^\)]*)\)", content) + if len(all_models) > 0: + model_tested = [] + for entry in all_models: + for line in entry.split(","): + name = line.strip() + if len(name) > 0: + model_tested.append(name) + return model_tested + + +def check_models_are_tested(module, test_file): + """Check models defined in module are tested in test_file.""" + # XxxModelMixin are not tested + defined_models = get_models(module) + tested_models = find_tested_models(test_file) + if tested_models is None: + if test_file.replace(os.path.sep, "/") in TEST_FILES_WITH_NO_COMMON_TESTS: + return + return [ + f"{test_file} should define `all_model_classes` to apply common tests to the models it tests. " + + "If this intentional, add the test filename to `TEST_FILES_WITH_NO_COMMON_TESTS` in the file " + + "`utils/check_repo.py`." + ] + failures = [] + for model_name, _ in defined_models: + if model_name not in tested_models and model_name not in IGNORE_NON_TESTED: + failures.append( + f"{model_name} is defined in {module.__name__} but is not tested in " + + f"{os.path.join(PATH_TO_TESTS, test_file)}. Add it to the all_model_classes in that file." + + "If common tests should not applied to that model, add its name to `IGNORE_NON_TESTED`" + + "in the file `utils/check_repo.py`." + ) + return failures + + +def check_all_models_are_tested(): + """Check all models are properly tested.""" + modules = get_model_modules() + test_files = get_model_test_files() + failures = [] + for module in modules: + test_file = [file for file in test_files if f"test_{module.__name__.split('.')[-1]}.py" in file] + if len(test_file) == 0: + failures.append(f"{module.__name__} does not have its corresponding test file {test_file}.") + elif len(test_file) > 1: + failures.append(f"{module.__name__} has several test files: {test_file}.") + else: + test_file = test_file[0] + new_failures = check_models_are_tested(module, test_file) + if new_failures is not None: + failures += new_failures + if len(failures) > 0: + raise Exception(f"There were {len(failures)} failures:\n" + "\n".join(failures)) + + +def get_all_auto_configured_models(): + """Return the list of all models in at least one auto class.""" + result = set() # To avoid duplicates we concatenate all model classes in a set. + if is_torch_available(): + for attr_name in dir(diffusers.models.auto.modeling_auto): + if attr_name.startswith("MODEL_") and attr_name.endswith("MAPPING_NAMES"): + result = result | set(get_values(getattr(diffusers.models.auto.modeling_auto, attr_name))) + if is_flax_available(): + for attr_name in dir(diffusers.models.auto.modeling_flax_auto): + if attr_name.startswith("FLAX_MODEL_") and attr_name.endswith("MAPPING_NAMES"): + result = result | set(get_values(getattr(diffusers.models.auto.modeling_flax_auto, attr_name))) + return list(result) + + +def ignore_unautoclassed(model_name): + """Rules to determine if `name` should be in an auto class.""" + # Special white list + if model_name in IGNORE_NON_AUTO_CONFIGURED: + return True + # Encoder and Decoder should be ignored + if "Encoder" in model_name or "Decoder" in model_name: + return True + return False + + +def check_models_are_auto_configured(module, all_auto_models): + """Check models defined in module are each in an auto class.""" + defined_models = get_models(module) + failures = [] + for model_name, _ in defined_models: + if model_name not in all_auto_models and not ignore_unautoclassed(model_name): + failures.append( + f"{model_name} is defined in {module.__name__} but is not present in any of the auto mapping. " + "If that is intended behavior, add its name to `IGNORE_NON_AUTO_CONFIGURED` in the file " + "`utils/check_repo.py`." + ) + return failures + + +def check_all_models_are_auto_configured(): + """Check all models are each in an auto class.""" + missing_backends = [] + if not is_torch_available(): + missing_backends.append("PyTorch") + if not is_flax_available(): + missing_backends.append("Flax") + if len(missing_backends) > 0: + missing = ", ".join(missing_backends) + if os.getenv("TRANSFORMERS_IS_CI", "").upper() in ENV_VARS_TRUE_VALUES: + raise Exception( + "Full quality checks require all backends to be installed (with `pip install -e .[dev]` in the " + f"Transformers repo, the following are missing: {missing}." + ) + else: + warnings.warn( + "Full quality checks require all backends to be installed (with `pip install -e .[dev]` in the " + f"Transformers repo, the following are missing: {missing}. While it's probably fine as long as you " + "didn't make any change in one of those backends modeling files, you should probably execute the " + "command above to be on the safe side." + ) + modules = get_model_modules() + all_auto_models = get_all_auto_configured_models() + failures = [] + for module in modules: + new_failures = check_models_are_auto_configured(module, all_auto_models) + if new_failures is not None: + failures += new_failures + if len(failures) > 0: + raise Exception(f"There were {len(failures)} failures:\n" + "\n".join(failures)) + + +_re_decorator = re.compile(r"^\s*@(\S+)\s+$") + + +def check_decorator_order(filename): + """Check that in the test file `filename` the slow decorator is always last.""" + with open(filename, "r", encoding="utf-8", newline="\n") as f: + lines = f.readlines() + decorator_before = None + errors = [] + for i, line in enumerate(lines): + search = _re_decorator.search(line) + if search is not None: + decorator_name = search.groups()[0] + if decorator_before is not None and decorator_name.startswith("parameterized"): + errors.append(i) + decorator_before = decorator_name + elif decorator_before is not None: + decorator_before = None + return errors + + +def check_all_decorator_order(): + """Check that in all test files, the slow decorator is always last.""" + errors = [] + for fname in os.listdir(PATH_TO_TESTS): + if fname.endswith(".py"): + filename = os.path.join(PATH_TO_TESTS, fname) + new_errors = check_decorator_order(filename) + errors += [f"- {filename}, line {i}" for i in new_errors] + if len(errors) > 0: + msg = "\n".join(errors) + raise ValueError( + "The parameterized decorator (and its variants) should always be first, but this is not the case in the" + f" following files:\n{msg}" + ) + + +def find_all_documented_objects(): + """Parse the content of all doc files to detect which classes and functions it documents""" + documented_obj = [] + for doc_file in Path(PATH_TO_DOC).glob("**/*.rst"): + with open(doc_file, "r", encoding="utf-8", newline="\n") as f: + content = f.read() + raw_doc_objs = re.findall(r"(?:autoclass|autofunction):: transformers.(\S+)\s+", content) + documented_obj += [obj.split(".")[-1] for obj in raw_doc_objs] + for doc_file in Path(PATH_TO_DOC).glob("**/*.md"): + with open(doc_file, "r", encoding="utf-8", newline="\n") as f: + content = f.read() + raw_doc_objs = re.findall(r"\[\[autodoc\]\]\s+(\S+)\s+", content) + documented_obj += [obj.split(".")[-1] for obj in raw_doc_objs] + return documented_obj + + +# One good reason for not being documented is to be deprecated. Put in this list deprecated objects. +DEPRECATED_OBJECTS = [ + "AutoModelWithLMHead", + "BartPretrainedModel", + "DataCollator", + "DataCollatorForSOP", + "GlueDataset", + "GlueDataTrainingArguments", + "LineByLineTextDataset", + "LineByLineWithRefDataset", + "LineByLineWithSOPTextDataset", + "PretrainedBartModel", + "PretrainedFSMTModel", + "SingleSentenceClassificationProcessor", + "SquadDataTrainingArguments", + "SquadDataset", + "SquadExample", + "SquadFeatures", + "SquadV1Processor", + "SquadV2Processor", + "TFAutoModelWithLMHead", + "TFBartPretrainedModel", + "TextDataset", + "TextDatasetForNextSentencePrediction", + "Wav2Vec2ForMaskedLM", + "Wav2Vec2Tokenizer", + "glue_compute_metrics", + "glue_convert_examples_to_features", + "glue_output_modes", + "glue_processors", + "glue_tasks_num_labels", + "squad_convert_examples_to_features", + "xnli_compute_metrics", + "xnli_output_modes", + "xnli_processors", + "xnli_tasks_num_labels", + "TFTrainer", + "TFTrainingArguments", +] + +# Exceptionally, some objects should not be documented after all rules passed. +# ONLY PUT SOMETHING IN THIS LIST AS A LAST RESORT! +UNDOCUMENTED_OBJECTS = [ + "AddedToken", # This is a tokenizers class. + "BasicTokenizer", # Internal, should never have been in the main init. + "CharacterTokenizer", # Internal, should never have been in the main init. + "DPRPretrainedReader", # Like an Encoder. + "DummyObject", # Just picked by mistake sometimes. + "MecabTokenizer", # Internal, should never have been in the main init. + "ModelCard", # Internal type. + "SqueezeBertModule", # Internal building block (should have been called SqueezeBertLayer) + "TFDPRPretrainedReader", # Like an Encoder. + "TransfoXLCorpus", # Internal type. + "WordpieceTokenizer", # Internal, should never have been in the main init. + "absl", # External module + "add_end_docstrings", # Internal, should never have been in the main init. + "add_start_docstrings", # Internal, should never have been in the main init. + "cached_path", # Internal used for downloading models. + "convert_tf_weight_name_to_pt_weight_name", # Internal used to convert model weights + "logger", # Internal logger + "logging", # External module + "requires_backends", # Internal function +] + +# This list should be empty. Objects in it should get their own doc page. +SHOULD_HAVE_THEIR_OWN_PAGE = [ + # Benchmarks + "PyTorchBenchmark", + "PyTorchBenchmarkArguments", + "TensorFlowBenchmark", + "TensorFlowBenchmarkArguments", +] + + +def ignore_undocumented(name): + """Rules to determine if `name` should be undocumented.""" + # NOT DOCUMENTED ON PURPOSE. + # Constants uppercase are not documented. + if name.isupper(): + return True + # ModelMixins / Encoders / Decoders / Layers / Embeddings / Attention are not documented. + if ( + name.endswith("ModelMixin") + or name.endswith("Decoder") + or name.endswith("Encoder") + or name.endswith("Layer") + or name.endswith("Embeddings") + or name.endswith("Attention") + ): + return True + # Submodules are not documented. + if os.path.isdir(os.path.join(PATH_TO_DIFFUSERS, name)) or os.path.isfile( + os.path.join(PATH_TO_DIFFUSERS, f"{name}.py") + ): + return True + # All load functions are not documented. + if name.startswith("load_tf") or name.startswith("load_pytorch"): + return True + # is_xxx_available functions are not documented. + if name.startswith("is_") and name.endswith("_available"): + return True + # Deprecated objects are not documented. + if name in DEPRECATED_OBJECTS or name in UNDOCUMENTED_OBJECTS: + return True + # MMBT model does not really work. + if name.startswith("MMBT"): + return True + if name in SHOULD_HAVE_THEIR_OWN_PAGE: + return True + return False + + +def check_all_objects_are_documented(): + """Check all models are properly documented.""" + documented_objs = find_all_documented_objects() + modules = diffusers._modules + objects = [c for c in dir(diffusers) if c not in modules and not c.startswith("_")] + undocumented_objs = [c for c in objects if c not in documented_objs and not ignore_undocumented(c)] + if len(undocumented_objs) > 0: + raise Exception( + "The following objects are in the public init so should be documented:\n - " + + "\n - ".join(undocumented_objs) + ) + check_docstrings_are_in_md() + check_model_type_doc_match() + + +def check_model_type_doc_match(): + """Check all doc pages have a corresponding model type.""" + model_doc_folder = Path(PATH_TO_DOC) / "model_doc" + model_docs = [m.stem for m in model_doc_folder.glob("*.md")] + + model_types = list(diffusers.models.auto.configuration_auto.MODEL_NAMES_MAPPING.keys()) + model_types = [MODEL_TYPE_TO_DOC_MAPPING[m] if m in MODEL_TYPE_TO_DOC_MAPPING else m for m in model_types] + + errors = [] + for m in model_docs: + if m not in model_types and m != "auto": + close_matches = get_close_matches(m, model_types) + error_message = f"{m} is not a proper model identifier." + if len(close_matches) > 0: + close_matches = "/".join(close_matches) + error_message += f" Did you mean {close_matches}?" + errors.append(error_message) + + if len(errors) > 0: + raise ValueError( + "Some model doc pages do not match any existing model type:\n" + + "\n".join(errors) + + "\nYou can add any missing model type to the `MODEL_NAMES_MAPPING` constant in " + "models/auto/configuration_auto.py." + ) + + +# Re pattern to catch :obj:`xx`, :class:`xx`, :func:`xx` or :meth:`xx`. +_re_rst_special_words = re.compile(r":(?:obj|func|class|meth):`([^`]+)`") +# Re pattern to catch things between double backquotes. +_re_double_backquotes = re.compile(r"(^|[^`])``([^`]+)``([^`]|$)") +# Re pattern to catch example introduction. +_re_rst_example = re.compile(r"^\s*Example.*::\s*$", flags=re.MULTILINE) + + +def is_rst_docstring(docstring): + """ + Returns `True` if `docstring` is written in rst. + """ + if _re_rst_special_words.search(docstring) is not None: + return True + if _re_double_backquotes.search(docstring) is not None: + return True + if _re_rst_example.search(docstring) is not None: + return True + return False + + +def check_docstrings_are_in_md(): + """Check all docstrings are in md""" + files_with_rst = [] + for file in Path(PATH_TO_DIFFUSERS).glob("**/*.py"): + with open(file, "r") as f: + code = f.read() + docstrings = code.split('"""') + + for idx, docstring in enumerate(docstrings): + if idx % 2 == 0 or not is_rst_docstring(docstring): + continue + files_with_rst.append(file) + break + + if len(files_with_rst) > 0: + raise ValueError( + "The following files have docstrings written in rst:\n" + + "\n".join([f"- {f}" for f in files_with_rst]) + + "\nTo fix this run `doc-builder convert path_to_py_file` after installing `doc-builder`\n" + "(`pip install git+https://github.com/huggingface/doc-builder`)" + ) + + +def check_repo_quality(): + """Check all models are properly tested and documented.""" + print("Checking all models are included.") + check_model_list() + print("Checking all models are public.") + check_models_are_in_init() + print("Checking all models are properly tested.") + check_all_decorator_order() + check_all_models_are_tested() + print("Checking all objects are properly documented.") + check_all_objects_are_documented() + print("Checking all models are in at least one auto class.") + check_all_models_are_auto_configured() + + +if __name__ == "__main__": + check_repo_quality() diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_support_list.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_support_list.py new file mode 100644 index 0000000000000000000000000000000000000000..5d06f0cb92a3969e21595c262be5fd9d1fb0aab3 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_support_list.py @@ -0,0 +1,124 @@ +# coding=utf-8 +# Copyright 2024 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +""" +Utility that checks that modules like attention processors are listed in the documentation file. + +```bash +python utils/check_support_list.py +``` + +It has no auto-fix mode. +""" + +import os +import re + + +# All paths are set with the intent that you run this script from the root of the repo +REPO_PATH = "." + + +def read_documented_classes(doc_path, autodoc_regex=r"\[\[autodoc\]\]\s([^\n]+)"): + """ + Reads documented classes from a doc file using a regex to find lines like [[autodoc]] my.module.Class. + Returns a list of documented class names (just the class name portion). + """ + with open(os.path.join(REPO_PATH, doc_path), "r") as f: + doctext = f.read() + matches = re.findall(autodoc_regex, doctext) + return [match.split(".")[-1] for match in matches] + + +def read_source_classes(src_path, class_regex, exclude_conditions=None): + """ + Reads class names from a source file using a regex that captures class definitions. + Optionally exclude classes based on a list of conditions (functions that take class name and return bool). + """ + if exclude_conditions is None: + exclude_conditions = [] + with open(os.path.join(REPO_PATH, src_path), "r") as f: + doctext = f.read() + classes = re.findall(class_regex, doctext) + # Filter out classes that meet any of the exclude conditions + filtered_classes = [c for c in classes if not any(cond(c) for cond in exclude_conditions)] + return filtered_classes + + +def check_documentation(doc_path, src_path, doc_regex, src_regex, exclude_conditions=None): + """ + Generic function to check if all classes defined in `src_path` are documented in `doc_path`. + Returns a set of undocumented class names. + """ + documented = set(read_documented_classes(doc_path, doc_regex)) + source_classes = set(read_source_classes(src_path, src_regex, exclude_conditions=exclude_conditions)) + + # Find which classes in source are not documented in a deterministic way. + undocumented = sorted(source_classes - documented) + return undocumented + + +if __name__ == "__main__": + # Define the checks we need to perform + checks = { + "Attention Processors": { + "doc_path": "docs/source/en/api/attnprocessor.md", + "src_path": "src/diffusers/models/attention_processor.py", + "doc_regex": r"\[\[autodoc\]\]\s([^\n]+)", + "src_regex": r"class\s+(\w+Processor(?:\d*_?\d*))[:(]", + "exclude_conditions": [lambda c: "LoRA" in c, lambda c: c == "Attention"], + }, + "Image Processors": { + "doc_path": "docs/source/en/api/image_processor.md", + "src_path": "src/diffusers/image_processor.py", + "doc_regex": r"\[\[autodoc\]\]\s([^\n]+)", + "src_regex": r"class\s+(\w+Processor(?:\d*_?\d*))[:(]", + }, + "Activations": { + "doc_path": "docs/source/en/api/activations.md", + "src_path": "src/diffusers/models/activations.py", + "doc_regex": r"\[\[autodoc\]\]\s([^\n]+)", + "src_regex": r"class\s+(\w+)\s*\(.*?nn\.Module.*?\):", + }, + "Normalizations": { + "doc_path": "docs/source/en/api/normalization.md", + "src_path": "src/diffusers/models/normalization.py", + "doc_regex": r"\[\[autodoc\]\]\s([^\n]+)", + "src_regex": r"class\s+(\w+)\s*\(.*?nn\.Module.*?\):", + "exclude_conditions": [ + # Exclude LayerNorm as it's an intentional exception + lambda c: c == "LayerNorm" + ], + }, + "LoRA Mixins": { + "doc_path": "docs/source/en/api/loaders/lora.md", + "src_path": "src/diffusers/loaders/lora_pipeline.py", + "doc_regex": r"\[\[autodoc\]\]\s([^\n]+)", + "src_regex": r"class\s+(\w+LoraLoaderMixin(?:\d*_?\d*))[:(]", + }, + } + + missing_items = {} + for category, params in checks.items(): + undocumented = check_documentation( + doc_path=params["doc_path"], + src_path=params["src_path"], + doc_regex=params["doc_regex"], + src_regex=params["src_regex"], + exclude_conditions=params.get("exclude_conditions"), + ) + if undocumented: + missing_items[category] = undocumented + + # If we have any missing items, raise a single combined error + if missing_items: + error_msg = ["Some classes are not documented properly:\n"] + for category, classes in missing_items.items(): + error_msg.append(f"- {category}: {', '.join(sorted(classes))}") + raise ValueError("\n".join(error_msg)) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_table.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_table.py new file mode 100644 index 0000000000000000000000000000000000000000..83c29aa74eca042df81386a73c12ffaf128fc4c2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/check_table.py @@ -0,0 +1,185 @@ +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import argparse +import collections +import importlib.util +import os +import re + + +# All paths are set with the intent you should run this script from the root of the repo with the command +# python utils/check_table.py +TRANSFORMERS_PATH = "src/diffusers" +PATH_TO_DOCS = "docs/source/en" +REPO_PATH = "." + + +def _find_text_in_file(filename, start_prompt, end_prompt): + """ + Find the text in `filename` between a line beginning with `start_prompt` and before `end_prompt`, removing empty + lines. + """ + with open(filename, "r", encoding="utf-8", newline="\n") as f: + lines = f.readlines() + # Find the start prompt. + start_index = 0 + while not lines[start_index].startswith(start_prompt): + start_index += 1 + start_index += 1 + + end_index = start_index + while not lines[end_index].startswith(end_prompt): + end_index += 1 + end_index -= 1 + + while len(lines[start_index]) <= 1: + start_index += 1 + while len(lines[end_index]) <= 1: + end_index -= 1 + end_index += 1 + return "".join(lines[start_index:end_index]), start_index, end_index, lines + + +# Add here suffixes that are used to identify models, separated by | +ALLOWED_MODEL_SUFFIXES = "Model|Encoder|Decoder|ForConditionalGeneration" +# Regexes that match TF/Flax/PT model names. +_re_tf_models = re.compile(r"TF(.*)(?:Model|Encoder|Decoder|ForConditionalGeneration)") +_re_flax_models = re.compile(r"Flax(.*)(?:Model|Encoder|Decoder|ForConditionalGeneration)") +# Will match any TF or Flax model too so need to be in an else branch afterthe two previous regexes. +_re_pt_models = re.compile(r"(.*)(?:Model|Encoder|Decoder|ForConditionalGeneration)") + + +# This is to make sure the diffusers module imported is the one in the repo. +spec = importlib.util.spec_from_file_location( + "diffusers", + os.path.join(TRANSFORMERS_PATH, "__init__.py"), + submodule_search_locations=[TRANSFORMERS_PATH], +) +diffusers_module = spec.loader.load_module() + + +# Thanks to https://stackoverflow.com/questions/29916065/how-to-do-camelcase-split-in-python +def camel_case_split(identifier): + """Split a camelcased `identifier` into words.""" + matches = re.finditer(".+?(?:(?<=[a-z])(?=[A-Z])|(?<=[A-Z])(?=[A-Z][a-z])|$)", identifier) + return [m.group(0) for m in matches] + + +def _center_text(text, width): + text_length = 2 if text == "✅" or text == "❌" else len(text) + left_indent = (width - text_length) // 2 + right_indent = width - text_length - left_indent + return " " * left_indent + text + " " * right_indent + + +def get_model_table_from_auto_modules(): + """Generates an up-to-date model table from the content of the auto modules.""" + # Dictionary model names to config. + config_mapping_names = diffusers_module.models.auto.configuration_auto.CONFIG_MAPPING_NAMES + model_name_to_config = { + name: config_mapping_names[code] + for code, name in diffusers_module.MODEL_NAMES_MAPPING.items() + if code in config_mapping_names + } + model_name_to_prefix = {name: config.replace("ConfigMixin", "") for name, config in model_name_to_config.items()} + + # Dictionaries flagging if each model prefix has a slow/fast tokenizer, backend in PT/TF/Flax. + slow_tokenizers = collections.defaultdict(bool) + fast_tokenizers = collections.defaultdict(bool) + pt_models = collections.defaultdict(bool) + tf_models = collections.defaultdict(bool) + flax_models = collections.defaultdict(bool) + + # Let's lookup through all diffusers object (once). + for attr_name in dir(diffusers_module): + lookup_dict = None + if attr_name.endswith("Tokenizer"): + lookup_dict = slow_tokenizers + attr_name = attr_name[:-9] + elif attr_name.endswith("TokenizerFast"): + lookup_dict = fast_tokenizers + attr_name = attr_name[:-13] + elif _re_tf_models.match(attr_name) is not None: + lookup_dict = tf_models + attr_name = _re_tf_models.match(attr_name).groups()[0] + elif _re_flax_models.match(attr_name) is not None: + lookup_dict = flax_models + attr_name = _re_flax_models.match(attr_name).groups()[0] + elif _re_pt_models.match(attr_name) is not None: + lookup_dict = pt_models + attr_name = _re_pt_models.match(attr_name).groups()[0] + + if lookup_dict is not None: + while len(attr_name) > 0: + if attr_name in model_name_to_prefix.values(): + lookup_dict[attr_name] = True + break + # Try again after removing the last word in the name + attr_name = "".join(camel_case_split(attr_name)[:-1]) + + # Let's build that table! + model_names = list(model_name_to_config.keys()) + model_names.sort(key=str.lower) + columns = ["Model", "Tokenizer slow", "Tokenizer fast", "PyTorch support", "TensorFlow support", "Flax Support"] + # We'll need widths to properly display everything in the center (+2 is to leave one extra space on each side). + widths = [len(c) + 2 for c in columns] + widths[0] = max([len(name) for name in model_names]) + 2 + + # Build the table per se + table = "|" + "|".join([_center_text(c, w) for c, w in zip(columns, widths)]) + "|\n" + # Use ":-----:" format to center-aligned table cell texts + table += "|" + "|".join([":" + "-" * (w - 2) + ":" for w in widths]) + "|\n" + + check = {True: "✅", False: "❌"} + for name in model_names: + prefix = model_name_to_prefix[name] + line = [ + name, + check[slow_tokenizers[prefix]], + check[fast_tokenizers[prefix]], + check[pt_models[prefix]], + check[tf_models[prefix]], + check[flax_models[prefix]], + ] + table += "|" + "|".join([_center_text(l, w) for l, w in zip(line, widths)]) + "|\n" + return table + + +def check_model_table(overwrite=False): + """Check the model table in the index.rst is consistent with the state of the lib and maybe `overwrite`.""" + current_table, start_index, end_index, lines = _find_text_in_file( + filename=os.path.join(PATH_TO_DOCS, "index.md"), + start_prompt="", + ) + new_table = get_model_table_from_auto_modules() + + if current_table != new_table: + if overwrite: + with open(os.path.join(PATH_TO_DOCS, "index.md"), "w", encoding="utf-8", newline="\n") as f: + f.writelines(lines[:start_index] + [new_table] + lines[end_index:]) + else: + raise ValueError( + "The model table in the `index.md` has not been updated. Run `make fix-copies` to fix this." + ) + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument("--fix_and_overwrite", action="store_true", help="Whether to fix inconsistencies.") + args = parser.parse_args() + + check_model_table(args.fix_and_overwrite) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/custom_init_isort.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/custom_init_isort.py new file mode 100644 index 0000000000000000000000000000000000000000..791df0e78694496eef3e71e2aa0b1f0010791a64 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/custom_init_isort.py @@ -0,0 +1,330 @@ +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Utility that sorts the imports in the custom inits of Diffusers. Diffusers uses init files that delay the +import of an object to when it's actually needed. This is to avoid the main init importing all models, which would +make the line `import transformers` very slow when the user has all optional dependencies installed. The inits with +delayed imports have two halves: one defining a dictionary `_import_structure` which maps modules to the name of the +objects in each module, and one in `TYPE_CHECKING` which looks like a normal init for type-checkers. `isort` or `ruff` +properly sort the second half which looks like traditionl imports, the goal of this script is to sort the first half. + +Use from the root of the repo with: + +```bash +python utils/custom_init_isort.py +``` + +which will auto-sort the imports (used in `make style`). + +For a check only (as used in `make quality`) run: + +```bash +python utils/custom_init_isort.py --check_only +``` +""" + +import argparse +import os +import re +from typing import Any, Callable, List, Optional + + +# Path is defined with the intent you should run this script from the root of the repo. +PATH_TO_TRANSFORMERS = "src/diffusers" + +# Pattern that looks at the indentation in a line. +_re_indent = re.compile(r"^(\s*)\S") +# Pattern that matches `"key":" and puts `key` in group 0. +_re_direct_key = re.compile(r'^\s*"([^"]+)":') +# Pattern that matches `_import_structure["key"]` and puts `key` in group 0. +_re_indirect_key = re.compile(r'^\s*_import_structure\["([^"]+)"\]') +# Pattern that matches `"key",` and puts `key` in group 0. +_re_strip_line = re.compile(r'^\s*"([^"]+)",\s*$') +# Pattern that matches any `[stuff]` and puts `stuff` in group 0. +_re_bracket_content = re.compile(r"\[([^\]]+)\]") + + +def get_indent(line: str) -> str: + """Returns the indent in given line (as string).""" + search = _re_indent.search(line) + return "" if search is None else search.groups()[0] + + +def split_code_in_indented_blocks( + code: str, indent_level: str = "", start_prompt: Optional[str] = None, end_prompt: Optional[str] = None +) -> List[str]: + """ + Split some code into its indented blocks, starting at a given level. + + Args: + code (`str`): The code to split. + indent_level (`str`): The indent level (as string) to use for identifying the blocks to split. + start_prompt (`str`, *optional*): If provided, only starts splitting at the line where this text is. + end_prompt (`str`, *optional*): If provided, stops splitting at a line where this text is. + + Warning: + The text before `start_prompt` or after `end_prompt` (if provided) is not ignored, just not split. The input `code` + can thus be retrieved by joining the result. + + Returns: + `List[str]`: The list of blocks. + """ + # Let's split the code into lines and move to start_index. + index = 0 + lines = code.split("\n") + if start_prompt is not None: + while not lines[index].startswith(start_prompt): + index += 1 + blocks = ["\n".join(lines[:index])] + else: + blocks = [] + + # This variable contains the block treated at a given time. + current_block = [lines[index]] + index += 1 + # We split into blocks until we get to the `end_prompt` (or the end of the file). + while index < len(lines) and (end_prompt is None or not lines[index].startswith(end_prompt)): + # We have a non-empty line with the proper indent -> start of a new block + if len(lines[index]) > 0 and get_indent(lines[index]) == indent_level: + # Store the current block in the result and rest. There are two cases: the line is part of the block (like + # a closing parenthesis) or not. + if len(current_block) > 0 and get_indent(current_block[-1]).startswith(indent_level + " "): + # Line is part of the current block + current_block.append(lines[index]) + blocks.append("\n".join(current_block)) + if index < len(lines) - 1: + current_block = [lines[index + 1]] + index += 1 + else: + current_block = [] + else: + # Line is not part of the current block + blocks.append("\n".join(current_block)) + current_block = [lines[index]] + else: + # Just add the line to the current block + current_block.append(lines[index]) + index += 1 + + # Adds current block if it's nonempty. + if len(current_block) > 0: + blocks.append("\n".join(current_block)) + + # Add final block after end_prompt if provided. + if end_prompt is not None and index < len(lines): + blocks.append("\n".join(lines[index:])) + + return blocks + + +def ignore_underscore_and_lowercase(key: Callable[[Any], str]) -> Callable[[Any], str]: + """ + Wraps a key function (as used in a sort) to lowercase and ignore underscores. + """ + + def _inner(x): + return key(x).lower().replace("_", "") + + return _inner + + +def sort_objects(objects: List[Any], key: Optional[Callable[[Any], str]] = None) -> List[Any]: + """ + Sort a list of objects following the rules of isort (all uppercased first, camel-cased second and lower-cased + last). + + Args: + objects (`List[Any]`): + The list of objects to sort. + key (`Callable[[Any], str]`, *optional*): + A function taking an object as input and returning a string, used to sort them by alphabetical order. + If not provided, will default to noop (so a `key` must be provided if the `objects` are not of type string). + + Returns: + `List[Any]`: The sorted list with the same elements as in the inputs + """ + + # If no key is provided, we use a noop. + def noop(x): + return x + + if key is None: + key = noop + # Constants are all uppercase, they go first. + constants = [obj for obj in objects if key(obj).isupper()] + # Classes are not all uppercase but start with a capital, they go second. + classes = [obj for obj in objects if key(obj)[0].isupper() and not key(obj).isupper()] + # Functions begin with a lowercase, they go last. + functions = [obj for obj in objects if not key(obj)[0].isupper()] + + # Then we sort each group. + key1 = ignore_underscore_and_lowercase(key) + return sorted(constants, key=key1) + sorted(classes, key=key1) + sorted(functions, key=key1) + + +def sort_objects_in_import(import_statement: str) -> str: + """ + Sorts the imports in a single import statement. + + Args: + import_statement (`str`): The import statement in which to sort the imports. + + Returns: + `str`: The same as the input, but with objects properly sorted. + """ + + # This inner function sort imports between [ ]. + def _replace(match): + imports = match.groups()[0] + # If there is one import only, nothing to do. + if "," not in imports: + return f"[{imports}]" + keys = [part.strip().replace('"', "") for part in imports.split(",")] + # We will have a final empty element if the line finished with a comma. + if len(keys[-1]) == 0: + keys = keys[:-1] + return "[" + ", ".join([f'"{k}"' for k in sort_objects(keys)]) + "]" + + lines = import_statement.split("\n") + if len(lines) > 3: + # Here we have to sort internal imports that are on several lines (one per name): + # key: [ + # "object1", + # "object2", + # ... + # ] + + # We may have to ignore one or two lines on each side. + idx = 2 if lines[1].strip() == "[" else 1 + keys_to_sort = [(i, _re_strip_line.search(line).groups()[0]) for i, line in enumerate(lines[idx:-idx])] + sorted_indices = sort_objects(keys_to_sort, key=lambda x: x[1]) + sorted_lines = [lines[x[0] + idx] for x in sorted_indices] + return "\n".join(lines[:idx] + sorted_lines + lines[-idx:]) + elif len(lines) == 3: + # Here we have to sort internal imports that are on one separate line: + # key: [ + # "object1", "object2", ... + # ] + if _re_bracket_content.search(lines[1]) is not None: + lines[1] = _re_bracket_content.sub(_replace, lines[1]) + else: + keys = [part.strip().replace('"', "") for part in lines[1].split(",")] + # We will have a final empty element if the line finished with a comma. + if len(keys[-1]) == 0: + keys = keys[:-1] + lines[1] = get_indent(lines[1]) + ", ".join([f'"{k}"' for k in sort_objects(keys)]) + return "\n".join(lines) + else: + # Finally we have to deal with imports fitting on one line + import_statement = _re_bracket_content.sub(_replace, import_statement) + return import_statement + + +def sort_imports(file: str, check_only: bool = True): + """ + Sort the imports defined in the `_import_structure` of a given init. + + Args: + file (`str`): The path to the init to check/fix. + check_only (`bool`, *optional*, defaults to `True`): Whether or not to just check (and not auto-fix) the init. + """ + with open(file, encoding="utf-8") as f: + code = f.read() + + # If the file is not a custom init, there is nothing to do. + if "_import_structure" not in code: + return + + # Blocks of indent level 0 + main_blocks = split_code_in_indented_blocks( + code, start_prompt="_import_structure = {", end_prompt="if TYPE_CHECKING:" + ) + + # We ignore block 0 (everything untils start_prompt) and the last block (everything after end_prompt). + for block_idx in range(1, len(main_blocks) - 1): + # Check if the block contains some `_import_structure`s thingy to sort. + block = main_blocks[block_idx] + block_lines = block.split("\n") + + # Get to the start of the imports. + line_idx = 0 + while line_idx < len(block_lines) and "_import_structure" not in block_lines[line_idx]: + # Skip dummy import blocks + if "import dummy" in block_lines[line_idx]: + line_idx = len(block_lines) + else: + line_idx += 1 + if line_idx >= len(block_lines): + continue + + # Ignore beginning and last line: they don't contain anything. + internal_block_code = "\n".join(block_lines[line_idx:-1]) + indent = get_indent(block_lines[1]) + # Slit the internal block into blocks of indent level 1. + internal_blocks = split_code_in_indented_blocks(internal_block_code, indent_level=indent) + # We have two categories of import key: list or _import_structure[key].append/extend + pattern = _re_direct_key if "_import_structure = {" in block_lines[0] else _re_indirect_key + # Grab the keys, but there is a trap: some lines are empty or just comments. + keys = [(pattern.search(b).groups()[0] if pattern.search(b) is not None else None) for b in internal_blocks] + # We only sort the lines with a key. + keys_to_sort = [(i, key) for i, key in enumerate(keys) if key is not None] + sorted_indices = [x[0] for x in sorted(keys_to_sort, key=lambda x: x[1])] + + # We reorder the blocks by leaving empty lines/comments as they were and reorder the rest. + count = 0 + reordered_blocks = [] + for i in range(len(internal_blocks)): + if keys[i] is None: + reordered_blocks.append(internal_blocks[i]) + else: + block = sort_objects_in_import(internal_blocks[sorted_indices[count]]) + reordered_blocks.append(block) + count += 1 + + # And we put our main block back together with its first and last line. + main_blocks[block_idx] = "\n".join(block_lines[:line_idx] + reordered_blocks + [block_lines[-1]]) + + if code != "\n".join(main_blocks): + if check_only: + return True + else: + print(f"Overwriting {file}.") + with open(file, "w", encoding="utf-8") as f: + f.write("\n".join(main_blocks)) + + +def sort_imports_in_all_inits(check_only=True): + """ + Sort the imports defined in the `_import_structure` of all inits in the repo. + + Args: + check_only (`bool`, *optional*, defaults to `True`): Whether or not to just check (and not auto-fix) the init. + """ + failures = [] + for root, _, files in os.walk(PATH_TO_TRANSFORMERS): + if "__init__.py" in files: + result = sort_imports(os.path.join(root, "__init__.py"), check_only=check_only) + if result: + failures = [os.path.join(root, "__init__.py")] + if len(failures) > 0: + raise ValueError(f"Would overwrite {len(failures)} files, run `make style`.") + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument("--check_only", action="store_true", help="Whether to only check or fix style.") + args = parser.parse_args() + + sort_imports_in_all_inits(check_only=args.check_only) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/extract_tests_from_mixin.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/extract_tests_from_mixin.py new file mode 100644 index 0000000000000000000000000000000000000000..c8b65b96ee16071042d93b66071367acad658d9c --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/extract_tests_from_mixin.py @@ -0,0 +1,61 @@ +import argparse +import inspect +import sys +from pathlib import Path +from typing import List, Type + + +root_dir = Path(__file__).parent.parent.absolute() +sys.path.insert(0, str(root_dir)) + +parser = argparse.ArgumentParser() +parser.add_argument("--type", type=str, default=None) +args = parser.parse_args() + + +def get_test_methods_from_class(cls: Type) -> List[str]: + """ + Get all test method names from a given class. + Only returns methods that start with 'test_'. + """ + test_methods = [] + for name, obj in inspect.getmembers(cls): + if name.startswith("test_") and inspect.isfunction(obj): + test_methods.append(name) + return sorted(test_methods) + + +def generate_pytest_pattern(test_methods: List[str]) -> str: + """Generate pytest pattern string for the -k flag.""" + return " or ".join(test_methods) + + +def generate_pattern_for_mixin(mixin_class: Type) -> str: + """ + Generate pytest pattern for a specific mixin class. + """ + if mixin_cls is None: + return "" + test_methods = get_test_methods_from_class(mixin_class) + return generate_pytest_pattern(test_methods) + + +if __name__ == "__main__": + mixin_cls = None + if args.type == "pipeline": + from tests.pipelines.test_pipelines_common import PipelineTesterMixin + + mixin_cls = PipelineTesterMixin + + elif args.type == "models": + from tests.models.test_modeling_common import ModelTesterMixin + + mixin_cls = ModelTesterMixin + + elif args.type == "lora": + from tests.lora.utils import PeftLoraLoaderMixinTests + + mixin_cls = PeftLoraLoaderMixinTests + + pattern = generate_pattern_for_mixin(mixin_cls) + print(pattern) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/fetch_latest_release_branch.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/fetch_latest_release_branch.py new file mode 100644 index 0000000000000000000000000000000000000000..41d5c472cbb98bf9f3ee7e4216d2926238330d01 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/fetch_latest_release_branch.py @@ -0,0 +1,73 @@ +# coding=utf-8 +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + + +import requests +from packaging.version import parse + + +# GitHub repository details +USER = "huggingface" +REPO = "diffusers" + + +def fetch_all_branches(user, repo): + branches = [] # List to store all branches + page = 1 # Start from first page + while True: + # Make a request to the GitHub API for the branches + response = requests.get( + f"https://api.github.com/repos/{user}/{repo}/branches", + params={"page": page}, + timeout=60, + ) + + # Check if the request was successful + if response.status_code == 200: + # Add the branches from the current page to the list + branches.extend([branch["name"] for branch in response.json()]) + + # Check if there is a 'next' link for pagination + if "next" in response.links: + page += 1 # Move to the next page + else: + break # Exit loop if there is no next page + else: + print("Failed to retrieve branches:", response.status_code) + break + + return branches + + +def main(): + # Fetch all branches + branches = fetch_all_branches(USER, REPO) + + # Filter branches. + # print(f"Total branches: {len(branches)}") + filtered_branches = [] + for branch in branches: + if branch.startswith("v") and ("-release" in branch or "-patch" in branch): + filtered_branches.append(branch) + # print(f"Filtered: {branch}") + + sorted_branches = sorted(filtered_branches, key=lambda x: parse(x.split("-")[0][1:]), reverse=True) + latest_branch = sorted_branches[0] + # print(f"Latest branch: {latest_branch}") + return latest_branch + + +if __name__ == "__main__": + print(main()) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/fetch_torch_cuda_pipeline_test_matrix.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/fetch_torch_cuda_pipeline_test_matrix.py new file mode 100644 index 0000000000000000000000000000000000000000..196f35628ac19922671724b85f80d75fc19fb436 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/fetch_torch_cuda_pipeline_test_matrix.py @@ -0,0 +1,99 @@ +import json +import logging +import os +from collections import defaultdict +from pathlib import Path + +from huggingface_hub import HfApi + +import diffusers + + +PATH_TO_REPO = Path(__file__).parent.parent.resolve() +ALWAYS_TEST_PIPELINE_MODULES = [ + "controlnet", + "controlnet_flux", + "controlnet_sd3", + "stable_diffusion", + "stable_diffusion_2", + "stable_diffusion_3", + "stable_diffusion_xl", + "ip_adapters", + "flux", +] +PIPELINE_USAGE_CUTOFF = int(os.getenv("PIPELINE_USAGE_CUTOFF", 50000)) + +logger = logging.getLogger(__name__) +api = HfApi() + + +def filter_pipelines(usage_dict, usage_cutoff=10000): + output = [] + for diffusers_object, usage in usage_dict.items(): + if usage < usage_cutoff: + continue + + is_diffusers_pipeline = hasattr(diffusers.pipelines, diffusers_object) + if not is_diffusers_pipeline: + continue + + output.append(diffusers_object) + + return output + + +def fetch_pipeline_objects(): + models = api.list_models(library="diffusers") + downloads = defaultdict(int) + + for model in models: + is_counted = False + for tag in model.tags: + if tag.startswith("diffusers:"): + is_counted = True + downloads[tag[len("diffusers:") :]] += model.downloads + + if not is_counted: + downloads["other"] += model.downloads + + # Remove 0 downloads + downloads = {k: v for k, v in downloads.items() if v > 0} + pipeline_objects = filter_pipelines(downloads, PIPELINE_USAGE_CUTOFF) + + return pipeline_objects + + +def fetch_pipeline_modules_to_test(): + try: + pipeline_objects = fetch_pipeline_objects() + except Exception as e: + logger.error(e) + raise RuntimeError("Unable to fetch model list from HuggingFace Hub.") + + test_modules = [] + for pipeline_name in pipeline_objects: + module = getattr(diffusers, pipeline_name) + + test_module = module.__module__.split(".")[-2].strip() + test_modules.append(test_module) + + return test_modules + + +def main(): + test_modules = fetch_pipeline_modules_to_test() + test_modules.extend(ALWAYS_TEST_PIPELINE_MODULES) + + # Get unique modules + test_modules = sorted(set(test_modules)) + print(json.dumps(test_modules)) + + save_path = f"{PATH_TO_REPO}/reports" + os.makedirs(save_path, exist_ok=True) + + with open(f"{save_path}/test-pipelines.json", "w") as f: + json.dump({"pipeline_test_modules": test_modules}, f) + + +if __name__ == "__main__": + main() diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/get_modified_files.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/get_modified_files.py new file mode 100644 index 0000000000000000000000000000000000000000..e392e50c12d3af270df748987be33ee6c3937901 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/get_modified_files.py @@ -0,0 +1,34 @@ +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# this script reports modified .py files under the desired list of top-level sub-dirs passed as a list of arguments, e.g.: +# python ./utils/get_modified_files.py utils src tests examples +# +# it uses git to find the forking point and which files were modified - i.e. files not under git won't be considered +# since the output of this script is fed into Makefile commands it doesn't print a newline after the results + +import re +import subprocess +import sys + + +fork_point_sha = subprocess.check_output("git merge-base main HEAD".split()).decode("utf-8") +modified_files = subprocess.check_output(f"git diff --name-only {fork_point_sha}".split()).decode("utf-8").split() + +joined_dirs = "|".join(sys.argv[1:]) +regex = re.compile(rf"^({joined_dirs}).*?\.py$") + +relevant_modified_files = [x for x in modified_files if regex.match(x)] +print(" ".join(relevant_modified_files), end="") diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/log_reports.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/log_reports.py new file mode 100644 index 0000000000000000000000000000000000000000..5575c9ba8415a73358fe48e3d0ac41b2188691d5 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/log_reports.py @@ -0,0 +1,139 @@ +import argparse +import json +import os +from datetime import date +from pathlib import Path + +from slack_sdk import WebClient +from tabulate import tabulate + + +MAX_LEN_MESSAGE = 2900 # slack endpoint has a limit of 3001 characters + +parser = argparse.ArgumentParser() +parser.add_argument("--slack_channel_name", default="diffusers-ci-nightly") + + +def main(slack_channel_name=None): + failed = [] + passed = [] + + group_info = [] + + total_num_failed = 0 + empty_file = False or len(list(Path().glob("*.log"))) == 0 + + total_empty_files = [] + + for log in Path().glob("*.log"): + section_num_failed = 0 + i = 0 + with open(log) as f: + for line in f: + line = json.loads(line) + i += 1 + if line.get("nodeid", "") != "": + test = line["nodeid"] + if line.get("duration", None) is not None: + duration = f"{line['duration']:.4f}" + if line.get("outcome", "") == "failed": + section_num_failed += 1 + failed.append([test, duration, log.name.split("_")[0]]) + total_num_failed += 1 + else: + passed.append([test, duration, log.name.split("_")[0]]) + empty_file = i == 0 + group_info.append([str(log), section_num_failed, failed]) + total_empty_files.append(empty_file) + os.remove(log) + failed = [] + text = ( + "🌞 There were no failures!" + if not any(total_empty_files) + else "Something went wrong there is at least one empty file - please check GH action results." + ) + no_error_payload = { + "type": "section", + "text": { + "type": "plain_text", + "text": text, + "emoji": True, + }, + } + + message = "" + payload = [ + { + "type": "header", + "text": { + "type": "plain_text", + "text": "🤗 Results of the Diffusers scheduled nightly tests.", + }, + }, + ] + if total_num_failed > 0: + for i, (name, num_failed, failed_tests) in enumerate(group_info): + if num_failed > 0: + if num_failed == 1: + message += f"*{name}: {num_failed} failed test*\n" + else: + message += f"*{name}: {num_failed} failed tests*\n" + failed_table = [] + for test in failed_tests: + failed_table.append(test[0].split("::")) + failed_table = tabulate( + failed_table, + headers=["Test Location", "Test Case", "Test Name"], + showindex="always", + tablefmt="grid", + maxcolwidths=[12, 12, 12], + ) + message += "\n```\n" + failed_table + "\n```" + + if total_empty_files[i]: + message += f"\n*{name}: Warning! Empty file - please check the GitHub action job *\n" + print(f"### {message}") + else: + payload.append(no_error_payload) + + if len(message) > MAX_LEN_MESSAGE: + print(f"Truncating long message from {len(message)} to {MAX_LEN_MESSAGE}") + message = message[:MAX_LEN_MESSAGE] + "..." + + if len(message) != 0: + md_report = { + "type": "section", + "text": {"type": "mrkdwn", "text": message}, + } + payload.append(md_report) + action_button = { + "type": "section", + "text": {"type": "mrkdwn", "text": "*For more details:*"}, + "accessory": { + "type": "button", + "text": {"type": "plain_text", "text": "Check Action results", "emoji": True}, + "url": f"https://github.com/huggingface/diffusers/actions/runs/{os.environ['GITHUB_RUN_ID']}", + }, + } + payload.append(action_button) + + date_report = { + "type": "context", + "elements": [ + { + "type": "plain_text", + "text": f"Nightly test results for {date.today()}", + }, + ], + } + payload.append(date_report) + + print(payload) + + client = WebClient(token=os.environ.get("SLACK_API_TOKEN")) + client.chat_postMessage(channel=f"#{slack_channel_name}", text=message, blocks=payload) + + +if __name__ == "__main__": + args = parser.parse_args() + main(args.slack_channel_name) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/notify_benchmarking_status.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/notify_benchmarking_status.py new file mode 100644 index 0000000000000000000000000000000000000000..c9c6ab485f597672e72f54418b3437209385d6a9 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/notify_benchmarking_status.py @@ -0,0 +1,56 @@ +# coding=utf-8 +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import argparse +import os + +import requests + + +# Configuration +GITHUB_REPO = "huggingface/diffusers" +GITHUB_RUN_ID = os.getenv("GITHUB_RUN_ID") +SLACK_WEBHOOK_URL = os.getenv("SLACK_WEBHOOK_URL") + + +def main(args): + action_url = f"https://github.com/{GITHUB_REPO}/actions/runs/{GITHUB_RUN_ID}" + if args.status == "success": + hub_path = "https://huggingface.co/datasets/diffusers/benchmarks/blob/main/collated_results.csv" + message = ( + "✅ New benchmark workflow successfully run.\n" + f"🕸️ GitHub Action URL: {action_url}.\n" + f"🤗 Check out the benchmarks here: {hub_path}." + ) + else: + message = ( + "❌ Something wrong happened in the benchmarking workflow.\n" + f"Check out the GitHub Action to know more: {action_url}." + ) + + payload = {"text": message} + response = requests.post(SLACK_WEBHOOK_URL, json=payload) + + if response.status_code == 200: + print("Notification sent to Slack successfully.") + else: + print("Failed to send notification to Slack.") + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument("--status", type=str, default="success", choices=["success", "failure"]) + args = parser.parse_args() + main(args) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/notify_community_pipelines_mirror.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/notify_community_pipelines_mirror.py new file mode 100644 index 0000000000000000000000000000000000000000..a7d3a31c988e2376cc10766bbec08dd2404a6cd7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/notify_community_pipelines_mirror.py @@ -0,0 +1,54 @@ +# coding=utf-8 +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import argparse +import os + +import requests + + +# Configuration +GITHUB_REPO = "huggingface/diffusers" +GITHUB_RUN_ID = os.getenv("GITHUB_RUN_ID") +SLACK_WEBHOOK_URL = os.getenv("SLACK_WEBHOOK_URL") +PATH_IN_REPO = os.getenv("PATH_IN_REPO") + + +def main(args): + action_url = f"https://github.com/{GITHUB_REPO}/actions/runs/{GITHUB_RUN_ID}" + if args.status == "success": + hub_path = f"https://huggingface.co/datasets/diffusers/community-pipelines-mirror/tree/main/{PATH_IN_REPO}" + message = ( + "✅ Community pipelines successfully mirrored.\n" + f"🕸️ GitHub Action URL: {action_url}.\n" + f"🤗 Hub location: {hub_path}." + ) + else: + message = f"❌ Something wrong happened. Check out the GitHub Action to know more: {action_url}." + + payload = {"text": message} + response = requests.post(SLACK_WEBHOOK_URL, json=payload) + + if response.status_code == 200: + print("Notification sent to Slack successfully.") + else: + print("Failed to send notification to Slack.") + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument("--status", type=str, default="success", choices=["success", "failure"]) + args = parser.parse_args() + main(args) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/notify_slack_about_release.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/notify_slack_about_release.py new file mode 100644 index 0000000000000000000000000000000000000000..0c7737a48ba4dba082dc88d068bf1355231b795b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/notify_slack_about_release.py @@ -0,0 +1,81 @@ +# coding=utf-8 +# Copyright 2024 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import os + +import requests + + +# Configuration +LIBRARY_NAME = "diffusers" +GITHUB_REPO = "huggingface/diffusers" +SLACK_WEBHOOK_URL = os.getenv("SLACK_WEBHOOK_URL") + + +def check_pypi_for_latest_release(library_name): + """Check PyPI for the latest release of the library.""" + response = requests.get(f"https://pypi.org/pypi/{library_name}/json", timeout=60) + if response.status_code == 200: + data = response.json() + return data["info"]["version"] + else: + print("Failed to fetch library details from PyPI.") + return None + + +def get_github_release_info(github_repo): + """Fetch the latest release info from GitHub.""" + url = f"https://api.github.com/repos/{github_repo}/releases/latest" + response = requests.get(url, timeout=60) + + if response.status_code == 200: + data = response.json() + return {"tag_name": data["tag_name"], "url": data["html_url"], "release_time": data["published_at"]} + + else: + print("Failed to fetch release info from GitHub.") + return None + + +def notify_slack(webhook_url, library_name, version, release_info): + """Send a notification to a Slack channel.""" + message = ( + f"🚀 New release for {library_name} available: version **{version}** 🎉\n" + f"📜 Release Notes: {release_info['url']}\n" + f"⏱️ Release time: {release_info['release_time']}" + ) + payload = {"text": message} + response = requests.post(webhook_url, json=payload) + + if response.status_code == 200: + print("Notification sent to Slack successfully.") + else: + print("Failed to send notification to Slack.") + + +def main(): + latest_version = check_pypi_for_latest_release(LIBRARY_NAME) + release_info = get_github_release_info(GITHUB_REPO) + parsed_version = release_info["tag_name"].replace("v", "") + + if latest_version and release_info and latest_version == parsed_version: + notify_slack(SLACK_WEBHOOK_URL, LIBRARY_NAME, latest_version, release_info) + else: + print(f"{latest_version=}, {release_info=}, {parsed_version=}") + raise ValueError("There were some problems.") + + +if __name__ == "__main__": + main() diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/overwrite_expected_slice.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/overwrite_expected_slice.py new file mode 100644 index 0000000000000000000000000000000000000000..723c1c98fc21321d9fa86b0d7c2024576eaff3cc --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/overwrite_expected_slice.py @@ -0,0 +1,90 @@ +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +import argparse +from collections import defaultdict + + +def overwrite_file(file, class_name, test_name, correct_line, done_test): + _id = f"{file}_{class_name}_{test_name}" + done_test[_id] += 1 + + with open(file, "r") as f: + lines = f.readlines() + + class_regex = f"class {class_name}(" + test_regex = f"{4 * ' '}def {test_name}(" + line_begin_regex = f"{8 * ' '}{correct_line.split()[0]}" + another_line_begin_regex = f"{16 * ' '}{correct_line.split()[0]}" + in_class = False + in_func = False + in_line = False + insert_line = False + count = 0 + spaces = 0 + + new_lines = [] + for line in lines: + if line.startswith(class_regex): + in_class = True + elif in_class and line.startswith(test_regex): + in_func = True + elif in_class and in_func and (line.startswith(line_begin_regex) or line.startswith(another_line_begin_regex)): + spaces = len(line.split(correct_line.split()[0])[0]) + count += 1 + + if count == done_test[_id]: + in_line = True + + if in_class and in_func and in_line: + if ")" not in line: + continue + else: + insert_line = True + + if in_class and in_func and in_line and insert_line: + new_lines.append(f"{spaces * ' '}{correct_line}") + in_class = in_func = in_line = insert_line = False + else: + new_lines.append(line) + + with open(file, "w") as f: + for line in new_lines: + f.write(line) + + +def main(correct, fail=None): + if fail is not None: + with open(fail, "r") as f: + test_failures = {l.strip() for l in f.readlines()} + else: + test_failures = None + + with open(correct, "r") as f: + correct_lines = f.readlines() + + done_tests = defaultdict(int) + for line in correct_lines: + file, class_name, test_name, correct_line = line.split("::") + if test_failures is None or "::".join([file, class_name, test_name]) in test_failures: + overwrite_file(file, class_name, test_name, correct_line, done_tests) + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument("--correct_filename", help="filename of tests with expected result") + parser.add_argument("--fail_filename", help="filename of test failures", type=str, default=None) + args = parser.parse_args() + + main(args.correct_filename, args.fail_filename) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/print_env.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/print_env.py new file mode 100644 index 0000000000000000000000000000000000000000..2d2acb59d5cce4044bd3403f615d4e915b221b5b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/print_env.py @@ -0,0 +1,63 @@ +#!/usr/bin/env python3 + +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +# this script dumps information about the environment + +import os +import platform +import sys + + +os.environ["TF_CPP_MIN_LOG_LEVEL"] = "3" + +print("Python version:", sys.version) + +print("OS platform:", platform.platform()) +print("OS architecture:", platform.machine()) + +try: + import torch + + print("Torch version:", torch.__version__) + print("Cuda available:", torch.cuda.is_available()) + if torch.cuda.is_available(): + print("Cuda version:", torch.version.cuda) + print("CuDNN version:", torch.backends.cudnn.version()) + print("Number of GPUs available:", torch.cuda.device_count()) + device_properties = torch.cuda.get_device_properties(0) + total_memory = device_properties.total_memory / (1024**3) + print(f"CUDA memory: {total_memory} GB") + + print("XPU available:", hasattr(torch, "xpu") and torch.xpu.is_available()) + if hasattr(torch, "xpu") and torch.xpu.is_available(): + print("XPU model:", torch.xpu.get_device_properties(0).name) + print("XPU compiler version:", torch.version.xpu) + print("Number of XPUs available:", torch.xpu.device_count()) + device_properties = torch.xpu.get_device_properties(0) + total_memory = device_properties.total_memory / (1024**3) + print(f"XPU memory: {total_memory} GB") + + +except ImportError: + print("Torch version:", None) + +try: + import transformers + + print("transformers version:", transformers.__version__) +except ImportError: + print("transformers version:", None) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/release.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/release.py new file mode 100644 index 0000000000000000000000000000000000000000..a0800b99fbebd9d2956b64fd92d93490e36f9a41 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/release.py @@ -0,0 +1,162 @@ +# coding=utf-8 +# Copyright 2021 The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import argparse +import os +import re + +import packaging.version + + +PATH_TO_EXAMPLES = "examples/" +REPLACE_PATTERNS = { + "examples": (re.compile(r'^check_min_version\("[^"]+"\)\s*$', re.MULTILINE), 'check_min_version("VERSION")\n'), + "init": (re.compile(r'^__version__\s+=\s+"([^"]+)"\s*$', re.MULTILINE), '__version__ = "VERSION"\n'), + "setup": (re.compile(r'^(\s*)version\s*=\s*"[^"]+",', re.MULTILINE), r'\1version="VERSION",'), + "doc": (re.compile(r'^(\s*)release\s*=\s*"[^"]+"$', re.MULTILINE), 'release = "VERSION"\n'), +} +REPLACE_FILES = { + "init": "src/diffusers/__init__.py", + "setup": "setup.py", +} +README_FILE = "README.md" + + +def update_version_in_file(fname, version, pattern): + """Update the version in one file using a specific pattern.""" + with open(fname, "r", encoding="utf-8", newline="\n") as f: + code = f.read() + re_pattern, replace = REPLACE_PATTERNS[pattern] + replace = replace.replace("VERSION", version) + code = re_pattern.sub(replace, code) + with open(fname, "w", encoding="utf-8", newline="\n") as f: + f.write(code) + + +def update_version_in_examples(version): + """Update the version in all examples files.""" + for folder, directories, fnames in os.walk(PATH_TO_EXAMPLES): + # Removing some of the folders with non-actively maintained examples from the walk + if "research_projects" in directories: + directories.remove("research_projects") + if "legacy" in directories: + directories.remove("legacy") + for fname in fnames: + if fname.endswith(".py"): + update_version_in_file(os.path.join(folder, fname), version, pattern="examples") + + +def global_version_update(version, patch=False): + """Update the version in all needed files.""" + for pattern, fname in REPLACE_FILES.items(): + update_version_in_file(fname, version, pattern) + if not patch: + update_version_in_examples(version) + + +def clean_main_ref_in_model_list(): + """Replace the links from main doc tp stable doc in the model list of the README.""" + # If the introduction or the conclusion of the list change, the prompts may need to be updated. + _start_prompt = "🤗 Transformers currently provides the following architectures" + _end_prompt = "1. Want to contribute a new model?" + with open(README_FILE, "r", encoding="utf-8", newline="\n") as f: + lines = f.readlines() + + # Find the start of the list. + start_index = 0 + while not lines[start_index].startswith(_start_prompt): + start_index += 1 + start_index += 1 + + index = start_index + # Update the lines in the model list. + while not lines[index].startswith(_end_prompt): + if lines[index].startswith("1."): + lines[index] = lines[index].replace( + "https://huggingface.co/docs/diffusers/main/model_doc", + "https://huggingface.co/docs/diffusers/model_doc", + ) + index += 1 + + with open(README_FILE, "w", encoding="utf-8", newline="\n") as f: + f.writelines(lines) + + +def get_version(): + """Reads the current version in the __init__.""" + with open(REPLACE_FILES["init"], "r") as f: + code = f.read() + default_version = REPLACE_PATTERNS["init"][0].search(code).groups()[0] + return packaging.version.parse(default_version) + + +def pre_release_work(patch=False): + """Do all the necessary pre-release steps.""" + # First let's get the default version: base version if we are in dev, bump minor otherwise. + default_version = get_version() + if patch and default_version.is_devrelease: + raise ValueError("Can't create a patch version from the dev branch, checkout a released version!") + if default_version.is_devrelease: + default_version = default_version.base_version + elif patch: + default_version = f"{default_version.major}.{default_version.minor}.{default_version.micro + 1}" + else: + default_version = f"{default_version.major}.{default_version.minor + 1}.0" + + # Now let's ask nicely if that's the right one. + version = input(f"Which version are you releasing? [{default_version}]") + if len(version) == 0: + version = default_version + + print(f"Updating version to {version}.") + global_version_update(version, patch=patch) + + +# if not patch: +# print("Cleaning main README, don't forget to run `make fix-copies`.") +# clean_main_ref_in_model_list() + + +def post_release_work(): + """Do all the necessary post-release steps.""" + # First let's get the current version + current_version = get_version() + dev_version = f"{current_version.major}.{current_version.minor + 1}.0.dev0" + current_version = current_version.base_version + + # Check with the user we got that right. + version = input(f"Which version are we developing now? [{dev_version}]") + if len(version) == 0: + version = dev_version + + print(f"Updating version to {version}.") + global_version_update(version) + + +# print("Cleaning main README, don't forget to run `make fix-copies`.") +# clean_main_ref_in_model_list() + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument("--post_release", action="store_true", help="Whether this is pre or post release.") + parser.add_argument("--patch", action="store_true", help="Whether or not this is a patch release.") + args = parser.parse_args() + if not args.post_release: + pre_release_work(patch=args.patch) + elif args.patch: + print("Nothing to do after a patch :-)") + else: + post_release_work() diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/stale.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/stale.py new file mode 100644 index 0000000000000000000000000000000000000000..20cb6cabeb91aef145690985ec07edd85f14ccff --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/stale.py @@ -0,0 +1,69 @@ +# Copyright 2024 The HuggingFace Team, the AllenNLP library authors. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Script to close stale issue. Taken in part from the AllenNLP repository. +https://github.com/allenai/allennlp. +""" + +import os +from datetime import datetime as dt +from datetime import timezone + +from github import Github + + +LABELS_TO_EXEMPT = [ + "close-to-merge", + "good first issue", + "good second issue", + "good difficult issue", + "enhancement", + "new pipeline/model", + "new scheduler", + "wip", +] + + +def main(): + g = Github(os.environ["GITHUB_TOKEN"]) + repo = g.get_repo("huggingface/diffusers") + open_issues = repo.get_issues(state="open") + + for issue in open_issues: + labels = [label.name.lower() for label in issue.get_labels()] + if "stale" in labels: + comments = sorted(issue.get_comments(), key=lambda i: i.created_at, reverse=True) + last_comment = comments[0] if len(comments) > 0 else None + if last_comment is not None and last_comment.user.login != "github-actions[bot]": + # Opens the issue if someone other than Stalebot commented. + issue.edit(state="open") + issue.remove_from_labels("stale") + elif ( + (dt.now(timezone.utc) - issue.updated_at).days > 23 + and (dt.now(timezone.utc) - issue.created_at).days >= 30 + and not any(label in LABELS_TO_EXEMPT for label in labels) + ): + # Post a Stalebot notification after 23 days of inactivity. + issue.create_comment( + "This issue has been automatically marked as stale because it has not had " + "recent activity. If you think this still needs to be addressed " + "please comment on this thread.\n\nPlease note that issues that do not follow the " + "[contributing guidelines](https://github.com/huggingface/diffusers/blob/main/CONTRIBUTING.md) " + "are likely to be ignored." + ) + issue.add_to_labels("stale") + + +if __name__ == "__main__": + main() diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/tests_fetcher.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/tests_fetcher.py new file mode 100644 index 0000000000000000000000000000000000000000..abdc9fd409dbe85e3cf2f72cc32de617b2434ade --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/tests_fetcher.py @@ -0,0 +1,1128 @@ +# coding=utf-8 +# Copyright 2021 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +""" +Welcome to tests_fetcher V2. + +This util is designed to fetch tests to run on a PR so that only the tests impacted by the modifications are run, and +when too many models are being impacted, only run the tests of a subset of core models. It works like this. + +Stage 1: Identify the modified files. For jobs that run on the main branch, it's just the diff with the last commit. +On a PR, this takes all the files from the branching point to the current commit (so all modifications in a PR, not +just the last commit) but excludes modifications that are on docstrings or comments only. + +Stage 2: Extract the tests to run. This is done by looking at the imports in each module and test file: if module A +imports module B, then changing module B impacts module A, so the tests using module A should be run. We thus get the +dependencies of each model and then recursively builds the 'reverse' map of dependencies to get all modules and tests +impacted by a given file. We then only keep the tests (and only the core models tests if there are too many modules). + +Caveats: + - This module only filters tests by files (not individual tests) so it's better to have tests for different things + in different files. + - This module assumes inits are just importing things, not really building objects, so it's better to structure + them this way and move objects building in separate submodules. + +Usage: + +Base use to fetch the tests in a pull request + +```bash +python utils/tests_fetcher.py +``` + +Base use to fetch the tests on a the main branch (with diff from the last commit): + +```bash +python utils/tests_fetcher.py --diff_with_last_commit +``` +""" + +import argparse +import collections +import json +import os +import re +from contextlib import contextmanager +from pathlib import Path +from typing import Dict, List, Optional, Tuple, Union + +from git import Repo + + +PATH_TO_REPO = Path(__file__).parent.parent.resolve() +PATH_TO_EXAMPLES = PATH_TO_REPO / "examples" +PATH_TO_DIFFUSERS = PATH_TO_REPO / "src/diffusers" +PATH_TO_TESTS = PATH_TO_REPO / "tests" + +# Ignore fixtures in tests folder +# Ignore lora since they are always tested +MODULES_TO_IGNORE = ["fixtures", "lora"] + +IMPORTANT_PIPELINES = [ + "controlnet", + "stable_diffusion", + "stable_diffusion_2", + "stable_diffusion_xl", + "stable_video_diffusion", + "deepfloyd_if", + "kandinsky", + "kandinsky2_2", + "text_to_video_synthesis", + "wuerstchen", +] + + +@contextmanager +def checkout_commit(repo: Repo, commit_id: str): + """ + Context manager that checks out a given commit when entered, but gets back to the reference it was at on exit. + + Args: + repo (`git.Repo`): A git repository (for instance the Transformers repo). + commit_id (`str`): The commit reference to checkout inside the context manager. + """ + current_head = repo.head.commit if repo.head.is_detached else repo.head.ref + + try: + repo.git.checkout(commit_id) + yield + + finally: + repo.git.checkout(current_head) + + +def clean_code(content: str) -> str: + """ + Remove docstrings, empty line or comments from some code (used to detect if a diff is real or only concern + comments or docstrings). + + Args: + content (`str`): The code to clean + + Returns: + `str`: The cleaned code. + """ + # We need to deactivate autoformatting here to write escaped triple quotes (we cannot use real triple quotes or + # this would mess up the result if this function applied to this particular file). + # fmt: off + # Remove docstrings by splitting on triple " then triple ': + splits = content.split('\"\"\"') + content = "".join(splits[::2]) + splits = content.split("\'\'\'") + # fmt: on + content = "".join(splits[::2]) + + # Remove empty lines and comments + lines_to_keep = [] + for line in content.split("\n"): + # remove anything that is after a # sign. + line = re.sub("#.*$", "", line) + # remove white lines + if len(line) != 0 and not line.isspace(): + lines_to_keep.append(line) + return "\n".join(lines_to_keep) + + +def keep_doc_examples_only(content: str) -> str: + """ + Remove everything from the code content except the doc examples (used to determined if a diff should trigger doc + tests or not). + + Args: + content (`str`): The code to clean + + Returns: + `str`: The cleaned code. + """ + # Keep doc examples only by splitting on triple "`" + splits = content.split("```") + # Add leading and trailing "```" so the navigation is easier when compared to the original input `content` + content = "```" + "```".join(splits[1::2]) + "```" + + # Remove empty lines and comments + lines_to_keep = [] + for line in content.split("\n"): + # remove anything that is after a # sign. + line = re.sub("#.*$", "", line) + # remove white lines + if len(line) != 0 and not line.isspace(): + lines_to_keep.append(line) + return "\n".join(lines_to_keep) + + +def get_all_tests() -> List[str]: + """ + Walks the `tests` folder to return a list of files/subfolders. This is used to split the tests to run when using + parallelism. The split is: + + - folders under `tests`: (`tokenization`, `pipelines`, etc) except the subfolder `models` is excluded. + - folders under `tests/models`: `bert`, `gpt2`, etc. + - test files under `tests`: `test_modeling_common.py`, `test_tokenization_common.py`, etc. + """ + + # test folders/files directly under `tests` folder + tests = os.listdir(PATH_TO_TESTS) + tests = [f"tests/{f}" for f in tests if "__pycache__" not in f] + tests = sorted([f for f in tests if (PATH_TO_REPO / f).is_dir() or f.startswith("tests/test_")]) + + return tests + + +def diff_is_docstring_only(repo: Repo, branching_point: str, filename: str) -> bool: + """ + Check if the diff is only in docstrings (or comments and whitespace) in a filename. + + Args: + repo (`git.Repo`): A git repository (for instance the Transformers repo). + branching_point (`str`): The commit reference of where to compare for the diff. + filename (`str`): The filename where we want to know if the diff isonly in docstrings/comments. + + Returns: + `bool`: Whether the diff is docstring/comments only or not. + """ + folder = Path(repo.working_dir) + with checkout_commit(repo, branching_point): + with open(folder / filename, "r", encoding="utf-8") as f: + old_content = f.read() + + with open(folder / filename, "r", encoding="utf-8") as f: + new_content = f.read() + + old_content_clean = clean_code(old_content) + new_content_clean = clean_code(new_content) + + return old_content_clean == new_content_clean + + +def diff_contains_doc_examples(repo: Repo, branching_point: str, filename: str) -> bool: + """ + Check if the diff is only in code examples of the doc in a filename. + + Args: + repo (`git.Repo`): A git repository (for instance the Transformers repo). + branching_point (`str`): The commit reference of where to compare for the diff. + filename (`str`): The filename where we want to know if the diff is only in codes examples. + + Returns: + `bool`: Whether the diff is only in code examples of the doc or not. + """ + folder = Path(repo.working_dir) + with checkout_commit(repo, branching_point): + with open(folder / filename, "r", encoding="utf-8") as f: + old_content = f.read() + + with open(folder / filename, "r", encoding="utf-8") as f: + new_content = f.read() + + old_content_clean = keep_doc_examples_only(old_content) + new_content_clean = keep_doc_examples_only(new_content) + + return old_content_clean != new_content_clean + + +def get_diff(repo: Repo, base_commit: str, commits: List[str]) -> List[str]: + """ + Get the diff between a base commit and one or several commits. + + Args: + repo (`git.Repo`): + A git repository (for instance the Transformers repo). + base_commit (`str`): + The commit reference of where to compare for the diff. This is the current commit, not the branching point! + commits (`List[str]`): + The list of commits with which to compare the repo at `base_commit` (so the branching point). + + Returns: + `List[str]`: The list of Python files with a diff (files added, renamed or deleted are always returned, files + modified are returned if the diff in the file is not only in docstrings or comments, see + `diff_is_docstring_only`). + """ + print("\n### DIFF ###\n") + code_diff = [] + for commit in commits: + for diff_obj in commit.diff(base_commit): + # We always add new python files + if diff_obj.change_type == "A" and diff_obj.b_path.endswith(".py"): + code_diff.append(diff_obj.b_path) + # We check that deleted python files won't break corresponding tests. + elif diff_obj.change_type == "D" and diff_obj.a_path.endswith(".py"): + code_diff.append(diff_obj.a_path) + # Now for modified files + elif diff_obj.change_type in ["M", "R"] and diff_obj.b_path.endswith(".py"): + # In case of renames, we'll look at the tests using both the old and new name. + if diff_obj.a_path != diff_obj.b_path: + code_diff.extend([diff_obj.a_path, diff_obj.b_path]) + else: + # Otherwise, we check modifications are in code and not docstrings. + if diff_is_docstring_only(repo, commit, diff_obj.b_path): + print(f"Ignoring diff in {diff_obj.b_path} as it only concerns docstrings or comments.") + else: + code_diff.append(diff_obj.a_path) + + return code_diff + + +def get_modified_python_files(diff_with_last_commit: bool = False) -> List[str]: + """ + Return a list of python files that have been modified between: + + - the current head and the main branch if `diff_with_last_commit=False` (default) + - the current head and its parent commit otherwise. + + Returns: + `List[str]`: The list of Python files with a diff (files added, renamed or deleted are always returned, files + modified are returned if the diff in the file is not only in docstrings or comments, see + `diff_is_docstring_only`). + """ + repo = Repo(PATH_TO_REPO) + + if not diff_with_last_commit: + # Need to fetch refs for main using remotes when running with github actions. + upstream_main = repo.remotes.origin.refs.main + + print(f"main is at {upstream_main.commit}") + print(f"Current head is at {repo.head.commit}") + + branching_commits = repo.merge_base(upstream_main, repo.head) + for commit in branching_commits: + print(f"Branching commit: {commit}") + return get_diff(repo, repo.head.commit, branching_commits) + else: + print(f"main is at {repo.head.commit}") + parent_commits = repo.head.commit.parents + for commit in parent_commits: + print(f"Parent commit: {commit}") + return get_diff(repo, repo.head.commit, parent_commits) + + +def get_diff_for_doctesting(repo: Repo, base_commit: str, commits: List[str]) -> List[str]: + """ + Get the diff in doc examples between a base commit and one or several commits. + + Args: + repo (`git.Repo`): + A git repository (for instance the Transformers repo). + base_commit (`str`): + The commit reference of where to compare for the diff. This is the current commit, not the branching point! + commits (`List[str]`): + The list of commits with which to compare the repo at `base_commit` (so the branching point). + + Returns: + `List[str]`: The list of Python and Markdown files with a diff (files added or renamed are always returned, files + modified are returned if the diff in the file is only in doctest examples). + """ + print("\n### DIFF ###\n") + code_diff = [] + for commit in commits: + for diff_obj in commit.diff(base_commit): + # We only consider Python files and doc files. + if not diff_obj.b_path.endswith(".py") and not diff_obj.b_path.endswith(".md"): + continue + # We always add new python/md files + if diff_obj.change_type in ["A"]: + code_diff.append(diff_obj.b_path) + # Now for modified files + elif diff_obj.change_type in ["M", "R"]: + # In case of renames, we'll look at the tests using both the old and new name. + if diff_obj.a_path != diff_obj.b_path: + code_diff.extend([diff_obj.a_path, diff_obj.b_path]) + else: + # Otherwise, we check modifications contain some doc example(s). + if diff_contains_doc_examples(repo, commit, diff_obj.b_path): + code_diff.append(diff_obj.a_path) + else: + print(f"Ignoring diff in {diff_obj.b_path} as it doesn't contain any doc example.") + + return code_diff + + +def get_all_doctest_files() -> List[str]: + """ + Return the complete list of python and Markdown files on which we run doctest. + + At this moment, we restrict this to only take files from `src/` or `docs/source/en/` that are not in `utils/not_doctested.txt`. + + Returns: + `List[str]`: The complete list of Python and Markdown files on which we run doctest. + """ + py_files = [str(x.relative_to(PATH_TO_REPO)) for x in PATH_TO_REPO.glob("**/*.py")] + md_files = [str(x.relative_to(PATH_TO_REPO)) for x in PATH_TO_REPO.glob("**/*.md")] + test_files_to_run = py_files + md_files + + # only include files in `src` or `docs/source/en/` + test_files_to_run = [x for x in test_files_to_run if x.startswith(("src/", "docs/source/en/"))] + # not include init files + test_files_to_run = [x for x in test_files_to_run if not x.endswith(("__init__.py",))] + + # These are files not doctested yet. + with open("utils/not_doctested.txt") as fp: + not_doctested = {x.split(" ")[0] for x in fp.read().strip().split("\n")} + + # So far we don't have 100% coverage for doctest. This line will be removed once we achieve 100%. + test_files_to_run = [x for x in test_files_to_run if x not in not_doctested] + + return sorted(test_files_to_run) + + +def get_new_doctest_files(repo, base_commit, branching_commit) -> List[str]: + """ + Get the list of files that were removed from "utils/not_doctested.txt", between `base_commit` and + `branching_commit`. + + Returns: + `List[str]`: List of files that were removed from "utils/not_doctested.txt". + """ + for diff_obj in branching_commit.diff(base_commit): + # Ignores all but the "utils/not_doctested.txt" file. + if diff_obj.a_path != "utils/not_doctested.txt": + continue + # Loads the two versions + folder = Path(repo.working_dir) + with checkout_commit(repo, branching_commit): + with open(folder / "utils/not_doctested.txt", "r", encoding="utf-8") as f: + old_content = f.read() + with open(folder / "utils/not_doctested.txt", "r", encoding="utf-8") as f: + new_content = f.read() + # Compute the removed lines and return them + removed_content = {x.split(" ")[0] for x in old_content.split("\n")} - { + x.split(" ")[0] for x in new_content.split("\n") + } + return sorted(removed_content) + return [] + + +def get_doctest_files(diff_with_last_commit: bool = False) -> List[str]: + """ + Return a list of python and Markdown files where doc example have been modified between: + + - the current head and the main branch if `diff_with_last_commit=False` (default) + - the current head and its parent commit otherwise. + + Returns: + `List[str]`: The list of Python and Markdown files with a diff (files added or renamed are always returned, files + modified are returned if the diff in the file is only in doctest examples). + """ + repo = Repo(PATH_TO_REPO) + + test_files_to_run = [] # noqa + if not diff_with_last_commit: + upstream_main = repo.remotes.origin.refs.main + print(f"main is at {upstream_main.commit}") + print(f"Current head is at {repo.head.commit}") + + branching_commits = repo.merge_base(upstream_main, repo.head) + for commit in branching_commits: + print(f"Branching commit: {commit}") + test_files_to_run = get_diff_for_doctesting(repo, repo.head.commit, branching_commits) + else: + print(f"main is at {repo.head.commit}") + parent_commits = repo.head.commit.parents + for commit in parent_commits: + print(f"Parent commit: {commit}") + test_files_to_run = get_diff_for_doctesting(repo, repo.head.commit, parent_commits) + + all_test_files_to_run = get_all_doctest_files() + + # Add to the test files to run any removed entry from "utils/not_doctested.txt". + new_test_files = get_new_doctest_files(repo, repo.head.commit, upstream_main.commit) + test_files_to_run = list(set(test_files_to_run + new_test_files)) + + # Do not run slow doctest tests on CircleCI + with open("utils/slow_documentation_tests.txt") as fp: + slow_documentation_tests = set(fp.read().strip().split("\n")) + test_files_to_run = [ + x for x in test_files_to_run if x in all_test_files_to_run and x not in slow_documentation_tests + ] + + # Make sure we did not end up with a test file that was removed + test_files_to_run = [f for f in test_files_to_run if (PATH_TO_REPO / f).exists()] + + return sorted(test_files_to_run) + + +# (:?^|\n) -> Non-catching group for the beginning of the doc or a new line. +# \s*from\s+(\.+\S+)\s+import\s+([^\n]+) -> Line only contains from .xxx import yyy and we catch .xxx and yyy +# (?=\n) -> Look-ahead to a new line. We can't just put \n here or using find_all on this re will only catch every +# other import. +_re_single_line_relative_imports = re.compile(r"(?:^|\n)\s*from\s+(\.+\S+)\s+import\s+([^\n]+)(?=\n)") +# (:?^|\n) -> Non-catching group for the beginning of the doc or a new line. +# \s*from\s+(\.+\S+)\s+import\s+\(([^\)]+)\) -> Line continues with from .xxx import (yyy) and we catch .xxx and yyy +# yyy will take multiple lines otherwise there wouldn't be parenthesis. +_re_multi_line_relative_imports = re.compile(r"(?:^|\n)\s*from\s+(\.+\S+)\s+import\s+\(([^\)]+)\)") +# (:?^|\n) -> Non-catching group for the beginning of the doc or a new line. +# \s*from\s+transformers(\S*)\s+import\s+([^\n]+) -> Line only contains from transformers.xxx import yyy and we catch +# .xxx and yyy +# (?=\n) -> Look-ahead to a new line. We can't just put \n here or using find_all on this re will only catch every +# other import. +_re_single_line_direct_imports = re.compile(r"(?:^|\n)\s*from\s+diffusers(\S*)\s+import\s+([^\n]+)(?=\n)") +# (:?^|\n) -> Non-catching group for the beginning of the doc or a new line. +# \s*from\s+transformers(\S*)\s+import\s+\(([^\)]+)\) -> Line continues with from transformers.xxx import (yyy) and we +# catch .xxx and yyy. yyy will take multiple lines otherwise there wouldn't be parenthesis. +_re_multi_line_direct_imports = re.compile(r"(?:^|\n)\s*from\s+diffusers(\S*)\s+import\s+\(([^\)]+)\)") + + +def extract_imports(module_fname: str, cache: Dict[str, List[str]] = None) -> List[str]: + """ + Get the imports a given module makes. + + Args: + module_fname (`str`): + The name of the file of the module where we want to look at the imports (given relative to the root of + the repo). + cache (Dictionary `str` to `List[str]`, *optional*): + To speed up this function if it was previously called on `module_fname`, the cache of all previously + computed results. + + Returns: + `List[str]`: The list of module filenames imported in the input `module_fname` (a submodule we import from that + is a subfolder will give its init file). + """ + if cache is not None and module_fname in cache: + return cache[module_fname] + + with open(PATH_TO_REPO / module_fname, "r", encoding="utf-8") as f: + content = f.read() + + # Filter out all docstrings to not get imports in code examples. As before we need to deactivate formatting to + # keep this as escaped quotes and avoid this function failing on this file. + # fmt: off + splits = content.split('\"\"\"') + # fmt: on + content = "".join(splits[::2]) + + module_parts = str(module_fname).split(os.path.sep) + imported_modules = [] + + # Let's start with relative imports + relative_imports = _re_single_line_relative_imports.findall(content) + relative_imports = [ + (mod, imp) for mod, imp in relative_imports if "# tests_ignore" not in imp and imp.strip() != "(" + ] + multiline_relative_imports = _re_multi_line_relative_imports.findall(content) + relative_imports += [(mod, imp) for mod, imp in multiline_relative_imports if "# tests_ignore" not in imp] + + # We need to remove parts of the module name depending on the depth of the relative imports. + for module, imports in relative_imports: + level = 0 + while module.startswith("."): + module = module[1:] + level += 1 + + if len(module) > 0: + dep_parts = module_parts[: len(module_parts) - level] + module.split(".") + else: + dep_parts = module_parts[: len(module_parts) - level] + imported_module = os.path.sep.join(dep_parts) + imported_modules.append((imported_module, [imp.strip() for imp in imports.split(",")])) + + # Let's continue with direct imports + direct_imports = _re_single_line_direct_imports.findall(content) + direct_imports = [(mod, imp) for mod, imp in direct_imports if "# tests_ignore" not in imp and imp.strip() != "("] + multiline_direct_imports = _re_multi_line_direct_imports.findall(content) + direct_imports += [(mod, imp) for mod, imp in multiline_direct_imports if "# tests_ignore" not in imp] + + # We need to find the relative path of those imports. + for module, imports in direct_imports: + import_parts = module.split(".")[1:] # ignore the name of the repo since we add it below. + dep_parts = ["src", "diffusers"] + import_parts + imported_module = os.path.sep.join(dep_parts) + imported_modules.append((imported_module, [imp.strip() for imp in imports.split(",")])) + + result = [] + # Double check we get proper modules (either a python file or a folder with an init). + for module_file, imports in imported_modules: + if (PATH_TO_REPO / f"{module_file}.py").is_file(): + module_file = f"{module_file}.py" + elif (PATH_TO_REPO / module_file).is_dir() and (PATH_TO_REPO / module_file / "__init__.py").is_file(): + module_file = os.path.sep.join([module_file, "__init__.py"]) + imports = [imp for imp in imports if len(imp) > 0 and re.match("^[A-Za-z0-9_]*$", imp)] + if len(imports) > 0: + result.append((module_file, imports)) + + if cache is not None: + cache[module_fname] = result + + return result + + +def get_module_dependencies(module_fname: str, cache: Dict[str, List[str]] = None) -> List[str]: + """ + Refines the result of `extract_imports` to remove subfolders and get a proper list of module filenames: if a file + as an import `from utils import Foo, Bar`, with `utils` being a subfolder containing many files, this will traverse + the `utils` init file to check where those dependencies come from: for instance the files utils/foo.py and utils/bar.py. + + Warning: This presupposes that all intermediate inits are properly built (with imports from the respective + submodules) and work better if objects are defined in submodules and not the intermediate init (otherwise the + intermediate init is added, and inits usually have a lot of dependencies). + + Args: + module_fname (`str`): + The name of the file of the module where we want to look at the imports (given relative to the root of + the repo). + cache (Dictionary `str` to `List[str]`, *optional*): + To speed up this function if it was previously called on `module_fname`, the cache of all previously + computed results. + + Returns: + `List[str]`: The list of module filenames imported in the input `module_fname` (with submodule imports refined). + """ + dependencies = [] + imported_modules = extract_imports(module_fname, cache=cache) + # The while loop is to recursively traverse all inits we may encounter: we will add things as we go. + while len(imported_modules) > 0: + new_modules = [] + for module, imports in imported_modules: + # If we end up in an __init__ we are often not actually importing from this init (except in the case where + # the object is fully defined in the __init__) + if module.endswith("__init__.py"): + # So we get the imports from that init then try to find where our objects come from. + new_imported_modules = extract_imports(module, cache=cache) + for new_module, new_imports in new_imported_modules: + if any(i in new_imports for i in imports): + if new_module not in dependencies: + new_modules.append((new_module, [i for i in new_imports if i in imports])) + imports = [i for i in imports if i not in new_imports] + if len(imports) > 0: + # If there are any objects lefts, they may be a submodule + path_to_module = PATH_TO_REPO / module.replace("__init__.py", "") + dependencies.extend( + [ + os.path.join(module.replace("__init__.py", ""), f"{i}.py") + for i in imports + if (path_to_module / f"{i}.py").is_file() + ] + ) + imports = [i for i in imports if not (path_to_module / f"{i}.py").is_file()] + if len(imports) > 0: + # Then if there are still objects left, they are fully defined in the init, so we keep it as a + # dependency. + dependencies.append(module) + else: + dependencies.append(module) + + imported_modules = new_modules + + return dependencies + + +def create_reverse_dependency_tree() -> List[Tuple[str, str]]: + """ + Create a list of all edges (a, b) which mean that modifying a impacts b with a going over all module and test files. + """ + cache = {} + all_modules = list(PATH_TO_DIFFUSERS.glob("**/*.py")) + list(PATH_TO_TESTS.glob("**/*.py")) + all_modules = [str(mod.relative_to(PATH_TO_REPO)) for mod in all_modules] + edges = [(dep, mod) for mod in all_modules for dep in get_module_dependencies(mod, cache=cache)] + + return list(set(edges)) + + +def get_tree_starting_at(module: str, edges: List[Tuple[str, str]]) -> List[Union[str, List[str]]]: + """ + Returns the tree starting at a given module following all edges. + + Args: + module (`str`): The module that will be the root of the subtree we want. + edges (`List[Tuple[str, str]]`): The list of all edges of the tree. + + Returns: + `List[Union[str, List[str]]]`: The tree to print in the following format: [module, [list of edges + starting at module], [list of edges starting at the preceding level], ...] + """ + vertices_seen = [module] + new_edges = [edge for edge in edges if edge[0] == module and edge[1] != module and "__init__.py" not in edge[1]] + tree = [module] + while len(new_edges) > 0: + tree.append(new_edges) + final_vertices = list({edge[1] for edge in new_edges}) + vertices_seen.extend(final_vertices) + new_edges = [ + edge + for edge in edges + if edge[0] in final_vertices and edge[1] not in vertices_seen and "__init__.py" not in edge[1] + ] + + return tree + + +def print_tree_deps_of(module, all_edges=None): + """ + Prints the tree of modules depending on a given module. + + Args: + module (`str`): The module that will be the root of the subtree we want. + all_edges (`List[Tuple[str, str]]`, *optional*): + The list of all edges of the tree. Will be set to `create_reverse_dependency_tree()` if not passed. + """ + if all_edges is None: + all_edges = create_reverse_dependency_tree() + tree = get_tree_starting_at(module, all_edges) + + # The list of lines is a list of tuples (line_to_be_printed, module) + # Keeping the modules lets us know where to insert each new lines in the list. + lines = [(tree[0], tree[0])] + for index in range(1, len(tree)): + edges = tree[index] + start_edges = {edge[0] for edge in edges} + + for start in start_edges: + end_edges = {edge[1] for edge in edges if edge[0] == start} + # We will insert all those edges just after the line showing start. + pos = 0 + while lines[pos][1] != start: + pos += 1 + lines = lines[: pos + 1] + [(" " * (2 * index) + end, end) for end in end_edges] + lines[pos + 1 :] + + for line in lines: + # We don't print the refs that where just here to help build lines. + print(line[0]) + + +def init_test_examples_dependencies() -> Tuple[Dict[str, List[str]], List[str]]: + """ + The test examples do not import from the examples (which are just scripts, not modules) so we need some extra + care initializing the dependency map, which is the goal of this function. It initializes the dependency map for + example files by linking each example to the example test file for the example framework. + + Returns: + `Tuple[Dict[str, List[str]], List[str]]`: A tuple with two elements: the initialized dependency map which is a + dict test example file to list of example files potentially tested by that test file, and the list of all + example files (to avoid recomputing it later). + """ + test_example_deps = {} + all_examples = [] + for framework in ["flax", "pytorch", "tensorflow"]: + test_files = list((PATH_TO_EXAMPLES / framework).glob("test_*.py")) + all_examples.extend(test_files) + # Remove the files at the root of examples/framework since they are not proper examples (they are either utils + # or example test files). + examples = [ + f for f in (PATH_TO_EXAMPLES / framework).glob("**/*.py") if f.parent != PATH_TO_EXAMPLES / framework + ] + all_examples.extend(examples) + for test_file in test_files: + with open(test_file, "r", encoding="utf-8") as f: + content = f.read() + # Map all examples to the test files found in examples/framework. + test_example_deps[str(test_file.relative_to(PATH_TO_REPO))] = [ + str(e.relative_to(PATH_TO_REPO)) for e in examples if e.name in content + ] + # Also map the test files to themselves. + test_example_deps[str(test_file.relative_to(PATH_TO_REPO))].append( + str(test_file.relative_to(PATH_TO_REPO)) + ) + return test_example_deps, all_examples + + +def create_reverse_dependency_map() -> Dict[str, List[str]]: + """ + Create the dependency map from module/test filename to the list of modules/tests that depend on it recursively. + + Returns: + `Dict[str, List[str]]`: The reverse dependency map as a dictionary mapping filenames to all the filenames + depending on it recursively. This way the tests impacted by a change in file A are the test files in the list + corresponding to key A in this result. + """ + cache = {} + # Start from the example deps init. + example_deps, examples = init_test_examples_dependencies() + # Add all modules and all tests to all examples + all_modules = list(PATH_TO_DIFFUSERS.glob("**/*.py")) + list(PATH_TO_TESTS.glob("**/*.py")) + examples + all_modules = [str(mod.relative_to(PATH_TO_REPO)) for mod in all_modules] + # Compute the direct dependencies of all modules. + direct_deps = {m: get_module_dependencies(m, cache=cache) for m in all_modules} + direct_deps.update(example_deps) + + # This recurses the dependencies + something_changed = True + while something_changed: + something_changed = False + for m in all_modules: + for d in direct_deps[m]: + # We stop recursing at an init (cause we always end up in the main init and we don't want to add all + # files which the main init imports) + if d.endswith("__init__.py"): + continue + if d not in direct_deps: + raise ValueError(f"KeyError:{d}. From {m}") + new_deps = set(direct_deps[d]) - set(direct_deps[m]) + if len(new_deps) > 0: + direct_deps[m].extend(list(new_deps)) + something_changed = True + + # Finally we can build the reverse map. + reverse_map = collections.defaultdict(list) + for m in all_modules: + for d in direct_deps[m]: + reverse_map[d].append(m) + + # For inits, we don't do the reverse deps but the direct deps: if modifying an init, we want to make sure we test + # all the modules impacted by that init. + for m in [f for f in all_modules if f.endswith("__init__.py")]: + direct_deps = get_module_dependencies(m, cache=cache) + deps = sum([reverse_map[d] for d in direct_deps if not d.endswith("__init__.py")], direct_deps) + reverse_map[m] = list(set(deps) - {m}) + + return reverse_map + + +def create_module_to_test_map(reverse_map: Dict[str, List[str]] = None) -> Dict[str, List[str]]: + """ + Extract the tests from the reverse_dependency_map and potentially filters the model tests. + + Args: + reverse_map (`Dict[str, List[str]]`, *optional*): + The reverse dependency map as created by `create_reverse_dependency_map`. Will default to the result of + that function if not provided. + filter_pipelines (`bool`, *optional*, defaults to `False`): + Whether or not to filter pipeline tests to only include core pipelines if a file impacts a lot of models. + + Returns: + `Dict[str, List[str]]`: A dictionary that maps each file to the tests to execute if that file was modified. + """ + if reverse_map is None: + reverse_map = create_reverse_dependency_map() + + # Utility that tells us if a given file is a test (taking test examples into account) + def is_test(fname): + if fname.startswith("tests"): + return True + if fname.startswith("examples") and fname.split(os.path.sep)[-1].startswith("test"): + return True + return False + + # Build the test map + test_map = {module: [f for f in deps if is_test(f)] for module, deps in reverse_map.items()} + + return test_map + + +def check_imports_all_exist(): + """ + Isn't used per se by the test fetcher but might be used later as a quality check. Putting this here for now so the + code is not lost. This checks all imports in a given file do exist. + """ + cache = {} + all_modules = list(PATH_TO_DIFFUSERS.glob("**/*.py")) + list(PATH_TO_TESTS.glob("**/*.py")) + all_modules = [str(mod.relative_to(PATH_TO_REPO)) for mod in all_modules] + direct_deps = {m: get_module_dependencies(m, cache=cache) for m in all_modules} + + for module, deps in direct_deps.items(): + for dep in deps: + if not (PATH_TO_REPO / dep).is_file(): + print(f"{module} has dependency on {dep} which does not exist.") + + +def _print_list(l) -> str: + """ + Pretty print a list of elements with one line per element and a - starting each line. + """ + return "\n".join([f"- {f}" for f in l]) + + +def update_test_map_with_core_pipelines(json_output_file: str): + print(f"\n### ADD CORE PIPELINE TESTS ###\n{_print_list(IMPORTANT_PIPELINES)}") + with open(json_output_file, "rb") as fp: + test_map = json.load(fp) + + # Add core pipelines as their own test group + test_map["core_pipelines"] = " ".join( + sorted([str(PATH_TO_TESTS / f"pipelines/{pipe}") for pipe in IMPORTANT_PIPELINES]) + ) + + # If there are no existing pipeline tests save the map + if "pipelines" not in test_map: + with open(json_output_file, "w", encoding="UTF-8") as fp: + json.dump(test_map, fp, ensure_ascii=False) + + pipeline_tests = test_map.pop("pipelines") + pipeline_tests = pipeline_tests.split(" ") + + # Remove core pipeline tests from the fetched pipeline tests + updated_pipeline_tests = [] + for pipe in pipeline_tests: + if pipe == "tests/pipelines" or Path(pipe).parts[2] in IMPORTANT_PIPELINES: + continue + updated_pipeline_tests.append(pipe) + + if len(updated_pipeline_tests) > 0: + test_map["pipelines"] = " ".join(sorted(updated_pipeline_tests)) + + with open(json_output_file, "w", encoding="UTF-8") as fp: + json.dump(test_map, fp, ensure_ascii=False) + + +def create_json_map(test_files_to_run: List[str], json_output_file: Optional[str] = None): + """ + Creates a map from a list of tests to run to easily split them by category, when running parallelism of slow tests. + + Args: + test_files_to_run (`List[str]`): The list of tests to run. + json_output_file (`str`): The path where to store the built json map. + """ + if json_output_file is None: + return + + test_map = {} + for test_file in test_files_to_run: + # `test_file` is a path to a test folder/file, starting with `tests/`. For example, + # - `tests/models/bert/test_modeling_bert.py` or `tests/models/bert` + # - `tests/trainer/test_trainer.py` or `tests/trainer` + # - `tests/test_modeling_common.py` + names = test_file.split(os.path.sep) + module = names[1] + if module in MODULES_TO_IGNORE: + continue + + if len(names) > 2 or not test_file.endswith(".py"): + # test folders under `tests` or python files under them + # take the part like tokenization, `pipeline`, etc. for other test categories + key = os.path.sep.join(names[1:2]) + else: + # common test files directly under `tests/` + key = "common" + + if key not in test_map: + test_map[key] = [] + test_map[key].append(test_file) + + # sort the keys & values + keys = sorted(test_map.keys()) + test_map = {k: " ".join(sorted(test_map[k])) for k in keys} + + with open(json_output_file, "w", encoding="UTF-8") as fp: + json.dump(test_map, fp, ensure_ascii=False) + + +def infer_tests_to_run( + output_file: str, + diff_with_last_commit: bool = False, + json_output_file: Optional[str] = None, +): + """ + The main function called by the test fetcher. Determines the tests to run from the diff. + + Args: + output_file (`str`): + The path where to store the summary of the test fetcher analysis. Other files will be stored in the same + folder: + + - examples_test_list.txt: The list of examples tests to run. + - test_repo_utils.txt: Will indicate if the repo utils tests should be run or not. + - doctest_list.txt: The list of doctests to run. + + diff_with_last_commit (`bool`, *optional*, defaults to `False`): + Whether to analyze the diff with the last commit (for use on the main branch after a PR is merged) or with + the branching point from main (for use on each PR). + filter_models (`bool`, *optional*, defaults to `True`): + Whether or not to filter the tests to core models only, when a file modified results in a lot of model + tests. + json_output_file (`str`, *optional*): + The path where to store the json file mapping categories of tests to tests to run (used for parallelism or + the slow tests). + """ + modified_files = get_modified_python_files(diff_with_last_commit=diff_with_last_commit) + print(f"\n### MODIFIED FILES ###\n{_print_list(modified_files)}") + # Create the map that will give us all impacted modules. + reverse_map = create_reverse_dependency_map() + impacted_files = modified_files.copy() + for f in modified_files: + if f in reverse_map: + impacted_files.extend(reverse_map[f]) + + # Remove duplicates + impacted_files = sorted(set(impacted_files)) + print(f"\n### IMPACTED FILES ###\n{_print_list(impacted_files)}") + + # Grab the corresponding test files: + if any(x in modified_files for x in ["setup.py"]): + test_files_to_run = ["tests", "examples"] + + # in order to trigger pipeline tests even if no code change at all + if "tests/utils/tiny_model_summary.json" in modified_files: + test_files_to_run = ["tests"] + any(f.split(os.path.sep)[0] == "utils" for f in modified_files) + else: + # All modified tests need to be run. + test_files_to_run = [ + f for f in modified_files if f.startswith("tests") and f.split(os.path.sep)[-1].startswith("test") + ] + # Then we grab the corresponding test files. + test_map = create_module_to_test_map(reverse_map=reverse_map) + for f in modified_files: + if f in test_map: + test_files_to_run.extend(test_map[f]) + test_files_to_run = sorted(set(test_files_to_run)) + # Make sure we did not end up with a test file that was removed + test_files_to_run = [f for f in test_files_to_run if (PATH_TO_REPO / f).exists()] + + any(f.split(os.path.sep)[0] == "utils" for f in modified_files) + + examples_tests_to_run = [f for f in test_files_to_run if f.startswith("examples")] + test_files_to_run = [f for f in test_files_to_run if not f.startswith("examples")] + print(f"\n### TEST TO RUN ###\n{_print_list(test_files_to_run)}") + if len(test_files_to_run) > 0: + with open(output_file, "w", encoding="utf-8") as f: + f.write(" ".join(test_files_to_run)) + + # Create a map that maps test categories to test files, i.e. `models/bert` -> [...test_modeling_bert.py, ...] + + # Get all test directories (and some common test files) under `tests` and `tests/models` if `test_files_to_run` + # contains `tests` (i.e. when `setup.py` is changed). + if "tests" in test_files_to_run: + test_files_to_run = get_all_tests() + + create_json_map(test_files_to_run, json_output_file) + + print(f"\n### EXAMPLES TEST TO RUN ###\n{_print_list(examples_tests_to_run)}") + if len(examples_tests_to_run) > 0: + # We use `all` in the case `commit_flags["test_all"]` as well as in `create_circleci_config.py` for processing + if examples_tests_to_run == ["examples"]: + examples_tests_to_run = ["all"] + example_file = Path(output_file).parent / "examples_test_list.txt" + with open(example_file, "w", encoding="utf-8") as f: + f.write(" ".join(examples_tests_to_run)) + + +def filter_tests(output_file: str, filters: List[str]): + """ + Reads the content of the output file and filters out all the tests in a list of given folders. + + Args: + output_file (`str` or `os.PathLike`): The path to the output file of the tests fetcher. + filters (`List[str]`): A list of folders to filter. + """ + if not os.path.isfile(output_file): + print("No test file found.") + return + with open(output_file, "r", encoding="utf-8") as f: + test_files = f.read().split(" ") + + if len(test_files) == 0 or test_files == [""]: + print("No tests to filter.") + return + + if test_files == ["tests"]: + test_files = [os.path.join("tests", f) for f in os.listdir("tests") if f not in ["__init__.py"] + filters] + else: + test_files = [f for f in test_files if f.split(os.path.sep)[1] not in filters] + + with open(output_file, "w", encoding="utf-8") as f: + f.write(" ".join(test_files)) + + +def parse_commit_message(commit_message: str) -> Dict[str, bool]: + """ + Parses the commit message to detect if a command is there to skip, force all or part of the CI. + + Args: + commit_message (`str`): The commit message of the current commit. + + Returns: + `Dict[str, bool]`: A dictionary of strings to bools with keys the following keys: `"skip"`, + `"test_all_models"` and `"test_all"`. + """ + if commit_message is None: + return {"skip": False, "no_filter": False, "test_all": False} + + command_search = re.search(r"\[([^\]]*)\]", commit_message) + if command_search is not None: + command = command_search.groups()[0] + command = command.lower().replace("-", " ").replace("_", " ") + skip = command in ["ci skip", "skip ci", "circleci skip", "skip circleci"] + no_filter = set(command.split(" ")) == {"no", "filter"} + test_all = set(command.split(" ")) == {"test", "all"} + return {"skip": skip, "no_filter": no_filter, "test_all": test_all} + else: + return {"skip": False, "no_filter": False, "test_all": False} + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument( + "--output_file", type=str, default="test_list.txt", help="Where to store the list of tests to run" + ) + parser.add_argument( + "--json_output_file", + type=str, + default="test_map.json", + help="Where to store the tests to run in a dictionary format mapping test categories to test files", + ) + parser.add_argument( + "--diff_with_last_commit", + action="store_true", + help="To fetch the tests between the current commit and the last commit", + ) + parser.add_argument( + "--filter_tests", + action="store_true", + help="Will filter the pipeline/repo utils tests outside of the generated list of tests.", + ) + parser.add_argument( + "--print_dependencies_of", + type=str, + help="Will only print the tree of modules depending on the file passed.", + default=None, + ) + parser.add_argument( + "--commit_message", + type=str, + help="The commit message (which could contain a command to force all tests or skip the CI).", + default=None, + ) + args = parser.parse_args() + if args.print_dependencies_of is not None: + print_tree_deps_of(args.print_dependencies_of) + else: + repo = Repo(PATH_TO_REPO) + commit_message = repo.head.commit.message + commit_flags = parse_commit_message(commit_message) + if commit_flags["skip"]: + print("Force-skipping the CI") + quit() + if commit_flags["no_filter"]: + print("Running all tests fetched without filtering.") + if commit_flags["test_all"]: + print("Force-launching all tests") + + diff_with_last_commit = args.diff_with_last_commit + if not diff_with_last_commit and not repo.head.is_detached and repo.head.ref == repo.refs.main: + print("main branch detected, fetching tests against last commit.") + diff_with_last_commit = True + + if not commit_flags["test_all"]: + try: + infer_tests_to_run( + args.output_file, + diff_with_last_commit=diff_with_last_commit, + json_output_file=args.json_output_file, + ) + filter_tests(args.output_file, ["repo_utils"]) + update_test_map_with_core_pipelines(json_output_file=args.json_output_file) + + except Exception as e: + print(f"\nError when trying to grab the relevant tests: {e}\n\nRunning all tests.") + commit_flags["test_all"] = True + + if commit_flags["test_all"]: + with open(args.output_file, "w", encoding="utf-8") as f: + f.write("tests") + example_file = Path(args.output_file).parent / "examples_test_list.txt" + with open(example_file, "w", encoding="utf-8") as f: + f.write("all") + + test_files_to_run = get_all_tests() + create_json_map(test_files_to_run, args.json_output_file) + update_test_map_with_core_pipelines(json_output_file=args.json_output_file) diff --git a/tasks/tasksmith-48efdcc71e7d/environment/source/utils/update_metadata.py b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/update_metadata.py new file mode 100644 index 0000000000000000000000000000000000000000..4fde581d4170ef46b168c4cbf59671463d9666c7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/environment/source/utils/update_metadata.py @@ -0,0 +1,125 @@ +# coding=utf-8 +# Copyright 2025 The HuggingFace Inc. team. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. +""" +Utility that updates the metadata of the Diffusers library in the repository `huggingface/diffusers-metadata`. + +Usage for an update (as used by the GitHub action `update_metadata`): + +```bash +python utils/update_metadata.py +``` + +Script modified from: +https://github.com/huggingface/transformers/blob/main/utils/update_metadata.py +""" + +import argparse +import os +import tempfile + +import pandas as pd +from datasets import Dataset +from huggingface_hub import hf_hub_download, upload_folder + +from diffusers.pipelines.auto_pipeline import ( + AUTO_IMAGE2IMAGE_PIPELINES_MAPPING, + AUTO_INPAINT_PIPELINES_MAPPING, + AUTO_TEXT2IMAGE_PIPELINES_MAPPING, +) + + +PIPELINE_TAG_JSON = "pipeline_tags.json" + + +def get_supported_pipeline_table() -> dict: + """ + Generates a dictionary containing the supported auto classes for each pipeline type, + using the content of the auto modules. + """ + # All supported pipelines for automatic mapping. + all_supported_pipeline_classes = [ + (class_name.__name__, "text-to-image", "AutoPipelineForText2Image") + for _, class_name in AUTO_TEXT2IMAGE_PIPELINES_MAPPING.items() + ] + all_supported_pipeline_classes += [ + (class_name.__name__, "image-to-image", "AutoPipelineForImage2Image") + for _, class_name in AUTO_IMAGE2IMAGE_PIPELINES_MAPPING.items() + ] + all_supported_pipeline_classes += [ + (class_name.__name__, "image-to-image", "AutoPipelineForInpainting") + for _, class_name in AUTO_INPAINT_PIPELINES_MAPPING.items() + ] + all_supported_pipeline_classes = list(set(all_supported_pipeline_classes)) + all_supported_pipeline_classes.sort(key=lambda x: x[0]) + + data = {} + data["pipeline_class"] = [sample[0] for sample in all_supported_pipeline_classes] + data["pipeline_tag"] = [sample[1] for sample in all_supported_pipeline_classes] + data["auto_class"] = [sample[2] for sample in all_supported_pipeline_classes] + + return data + + +def update_metadata(commit_sha: str): + """ + Update the metadata for the Diffusers repo in `huggingface/diffusers-metadata`. + + Args: + commit_sha (`str`): The commit SHA on Diffusers corresponding to this update. + """ + pipelines_table = get_supported_pipeline_table() + pipelines_table = pd.DataFrame(pipelines_table) + pipelines_dataset = Dataset.from_pandas(pipelines_table) + + hub_pipeline_tags_json = hf_hub_download( + repo_id="huggingface/diffusers-metadata", + filename=PIPELINE_TAG_JSON, + repo_type="dataset", + ) + with open(hub_pipeline_tags_json) as f: + hub_pipeline_tags_json = f.read() + + with tempfile.TemporaryDirectory() as tmp_dir: + pipelines_dataset.to_json(os.path.join(tmp_dir, PIPELINE_TAG_JSON)) + + with open(os.path.join(tmp_dir, PIPELINE_TAG_JSON)) as f: + pipeline_tags_json = f.read() + + hub_pipeline_tags_equal = hub_pipeline_tags_json == pipeline_tags_json + if hub_pipeline_tags_equal: + print("No updates, not pushing the metadata files.") + return + + if commit_sha is not None: + commit_message = ( + f"Update with commit {commit_sha}\n\nSee: https://github.com/huggingface/diffusers/commit/{commit_sha}" + ) + else: + commit_message = "Update" + + upload_folder( + repo_id="huggingface/diffusers-metadata", + folder_path=tmp_dir, + repo_type="dataset", + commit_message=commit_message, + ) + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument("--commit_sha", default=None, type=str, help="The sha of the commit going with this update.") + args = parser.parse_args() + + update_metadata(args.commit_sha) diff --git a/tasks/tasksmith-48efdcc71e7d/instruction.md b/tasks/tasksmith-48efdcc71e7d/instruction.md new file mode 100644 index 0000000000000000000000000000000000000000..fa6da66c662be6f05de1fd35ca2d670820bae0a9 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/instruction.md @@ -0,0 +1,24 @@ +Add a new `SanaSprintImg2ImgPipeline` class to the diffusers library as an image-to-image variant of the existing `SanaSprintPipeline`. + +**Constructor:** accepts `tokenizer`, `text_encoder` (Gemma2), `vae` (AutoencoderDC), `transformer` (SanaTransformer2DModel), and `scheduler` (`SCMScheduler`, using the existing Sana Sprint SCM timestep and model-input conventions). The `vae_scale_factor` is derived from `vae.config.encoder_block_out_channels`. A `PixArtImageProcessor` is created with that scale factor. + +**`__call__` signature** (key parameters): `prompt`, `image` (the conditioning image), `strength` (float in [0, 1], default 0.6), `height`, `width`, `num_inference_steps` (default 2), `max_timesteps`, `intermediate_timesteps`, `guidance_scale`, `generator`, `latents`, `prompt_embeds`, `prompt_attention_mask`, `output_type` (`"pil"`, `"pt"`, or `"latent"`), `return_dict`, `callback_on_step_end`, `callback_on_step_end_tensor_inputs`, `use_resolution_binning`, `complex_human_instruction`. + +**Image conditioning:** The input image is preprocessed and VAE-encoded. Latents are initialized using the SCM formula: `cos(t) * image_latents + sin(t) * noise`, where `t` is the starting timestep, `image_latents` are the scaled VAE latents (`vae.encode * vae.config.scaling_factor * scheduler.config.sigma_data`), and `noise` is scaled by `scheduler.config.sigma_data`. If pre-generated `latents` are provided, image encoding is skipped entirely. + +**Strength:** controls how many denoising steps are used. Lower strength → fewer steps → output closer to the input image. The scheduler timesteps are trimmed from the front based on `strength`. Round the retained fraction of the requested denoising steps upward: with two requested steps, strength 0.4 retains one step, strength 0.5 retains one, and strength 0.9 retains two. A positive strength therefore retains at least one step. Strength zero retains no steps and raises `ValueError`. + +**Validation errors:** +- `strength` outside `[0.0, 1.0]` → `ValueError` +- `height` or `width` not divisible by 32 → `ValueError` (checked after optional resolution binning) +- Both `prompt` and `prompt_embeds` provided → `ValueError` +- Neither `prompt` nor `prompt_embeds` → `ValueError` +- `prompt_embeds` without `prompt_attention_mask` → `ValueError` + +**Output:** `SanaPipelineOutput(images=...)` when `return_dict=True`, or a 1-tuple when `return_dict=False`. Decoded images are returned as PIL images for `output_type="pil"` or as a PyTorch image tensor for `output_type="pt"`. When `output_type="latent"`, the raw latent tensor is returned without decoding. + +**Class attributes:** `model_cpu_offload_seq = "text_encoder->transformer->vae"`, `_callback_tensor_inputs = ["latents", "prompt_embeds"]`. + +**Exports:** `SanaSprintImg2ImgPipeline` must be importable from `diffusers` and from `diffusers.pipelines.sana`. A dummy stub must exist in `dummy_torch_and_transformers_objects.py`. + +Work in `/workspace`. Submit your fix in Python source files under `src/diffusers`. Preserve the other public behavior. The environment is offline; dependencies are preinstalled. Grading runs the relevant repository tests in a fresh environment, using your submitted source files. diff --git a/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/__init__.py b/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..8c4ae36c56542b157d1a9dc21577c1100b914dc2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/__init__.py @@ -0,0 +1,1229 @@ +__version__ = "0.34.0.dev0" + +from typing import TYPE_CHECKING + +from .utils import ( + DIFFUSERS_SLOW_IMPORT, + OptionalDependencyNotAvailable, + _LazyModule, + is_accelerate_available, + is_bitsandbytes_available, + is_flax_available, + is_gguf_available, + is_k_diffusion_available, + is_librosa_available, + is_note_seq_available, + is_onnx_available, + is_opencv_available, + is_optimum_quanto_available, + is_scipy_available, + is_sentencepiece_available, + is_torch_available, + is_torchao_available, + is_torchsde_available, + is_transformers_available, +) + + +# Lazy Import based on +# https://github.com/huggingface/transformers/blob/main/src/transformers/__init__.py + +# When adding a new object to this init, please add it to `_import_structure`. The `_import_structure` is a dictionary submodule to list of object names, +# and is used to defer the actual importing for when the objects are requested. +# This way `import diffusers` provides the names in the namespace without actually importing anything (and especially none of the backends). + +_import_structure = { + "configuration_utils": ["ConfigMixin"], + "hooks": [], + "loaders": ["FromOriginalModelMixin"], + "models": [], + "pipelines": [], + "quantizers.quantization_config": [], + "schedulers": [], + "utils": [ + "OptionalDependencyNotAvailable", + "is_flax_available", + "is_inflect_available", + "is_invisible_watermark_available", + "is_k_diffusion_available", + "is_k_diffusion_version", + "is_librosa_available", + "is_note_seq_available", + "is_onnx_available", + "is_scipy_available", + "is_torch_available", + "is_torchsde_available", + "is_transformers_available", + "is_transformers_version", + "is_unidecode_available", + "logging", + ], +} + +try: + if not is_torch_available() and not is_accelerate_available() and not is_bitsandbytes_available(): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_bitsandbytes_objects + + _import_structure["utils.dummy_bitsandbytes_objects"] = [ + name for name in dir(dummy_bitsandbytes_objects) if not name.startswith("_") + ] +else: + _import_structure["quantizers.quantization_config"].append("BitsAndBytesConfig") + +try: + if not is_torch_available() and not is_accelerate_available() and not is_gguf_available(): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_gguf_objects + + _import_structure["utils.dummy_gguf_objects"] = [ + name for name in dir(dummy_gguf_objects) if not name.startswith("_") + ] +else: + _import_structure["quantizers.quantization_config"].append("GGUFQuantizationConfig") + +try: + if not is_torch_available() and not is_accelerate_available() and not is_torchao_available(): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_torchao_objects + + _import_structure["utils.dummy_torchao_objects"] = [ + name for name in dir(dummy_torchao_objects) if not name.startswith("_") + ] +else: + _import_structure["quantizers.quantization_config"].append("TorchAoConfig") + +try: + if not is_torch_available() and not is_accelerate_available() and not is_optimum_quanto_available(): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_optimum_quanto_objects + + _import_structure["utils.dummy_optimum_quanto_objects"] = [ + name for name in dir(dummy_optimum_quanto_objects) if not name.startswith("_") + ] +else: + _import_structure["quantizers.quantization_config"].append("QuantoConfig") + +try: + if not is_onnx_available(): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_onnx_objects # noqa F403 + + _import_structure["utils.dummy_onnx_objects"] = [ + name for name in dir(dummy_onnx_objects) if not name.startswith("_") + ] + +else: + _import_structure["pipelines"].extend(["OnnxRuntimeModel"]) + +try: + if not is_torch_available(): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_pt_objects # noqa F403 + + _import_structure["utils.dummy_pt_objects"] = [name for name in dir(dummy_pt_objects) if not name.startswith("_")] + +else: + _import_structure["hooks"].extend( + [ + "FasterCacheConfig", + "HookRegistry", + "PyramidAttentionBroadcastConfig", + "apply_faster_cache", + "apply_pyramid_attention_broadcast", + ] + ) + _import_structure["models"].extend( + [ + "AllegroTransformer3DModel", + "AsymmetricAutoencoderKL", + "AuraFlowTransformer2DModel", + "AutoencoderDC", + "AutoencoderKL", + "AutoencoderKLAllegro", + "AutoencoderKLCogVideoX", + "AutoencoderKLCosmos", + "AutoencoderKLHunyuanVideo", + "AutoencoderKLLTXVideo", + "AutoencoderKLMagvit", + "AutoencoderKLMochi", + "AutoencoderKLTemporalDecoder", + "AutoencoderKLWan", + "AutoencoderOobleck", + "AutoencoderTiny", + "AutoModel", + "CacheMixin", + "CogVideoXTransformer3DModel", + "CogView3PlusTransformer2DModel", + "CogView4Transformer2DModel", + "ConsisIDTransformer3DModel", + "ConsistencyDecoderVAE", + "ControlNetModel", + "ControlNetUnionModel", + "ControlNetXSAdapter", + "CosmosTransformer3DModel", + "DiTTransformer2DModel", + "EasyAnimateTransformer3DModel", + "FluxControlNetModel", + "FluxMultiControlNetModel", + "FluxTransformer2DModel", + "HiDreamImageTransformer2DModel", + "HunyuanDiT2DControlNetModel", + "HunyuanDiT2DModel", + "HunyuanDiT2DMultiControlNetModel", + "HunyuanVideoFramepackTransformer3DModel", + "HunyuanVideoTransformer3DModel", + "I2VGenXLUNet", + "Kandinsky3UNet", + "LatteTransformer3DModel", + "LTXVideoTransformer3DModel", + "Lumina2Transformer2DModel", + "LuminaNextDiT2DModel", + "MochiTransformer3DModel", + "ModelMixin", + "MotionAdapter", + "MultiAdapter", + "MultiControlNetModel", + "OmniGenTransformer2DModel", + "PixArtTransformer2DModel", + "PriorTransformer", + "SanaControlNetModel", + "SanaTransformer2DModel", + "SD3ControlNetModel", + "SD3MultiControlNetModel", + "SD3Transformer2DModel", + "SparseControlNetModel", + "StableAudioDiTModel", + "StableCascadeUNet", + "T2IAdapter", + "T5FilmDecoder", + "Transformer2DModel", + "TransformerTemporalModel", + "UNet1DModel", + "UNet2DConditionModel", + "UNet2DModel", + "UNet3DConditionModel", + "UNetControlNetXSModel", + "UNetMotionModel", + "UNetSpatioTemporalConditionModel", + "UVit2DModel", + "VQModel", + "WanTransformer3DModel", + ] + ) + _import_structure["optimization"] = [ + "get_constant_schedule", + "get_constant_schedule_with_warmup", + "get_cosine_schedule_with_warmup", + "get_cosine_with_hard_restarts_schedule_with_warmup", + "get_linear_schedule_with_warmup", + "get_polynomial_decay_schedule_with_warmup", + "get_scheduler", + ] + _import_structure["pipelines"].extend( + [ + "AudioPipelineOutput", + "AutoPipelineForImage2Image", + "AutoPipelineForInpainting", + "AutoPipelineForText2Image", + "ConsistencyModelPipeline", + "DanceDiffusionPipeline", + "DDIMPipeline", + "DDPMPipeline", + "DiffusionPipeline", + "DiTPipeline", + "ImagePipelineOutput", + "KarrasVePipeline", + "LDMPipeline", + "LDMSuperResolutionPipeline", + "PNDMPipeline", + "RePaintPipeline", + "ScoreSdeVePipeline", + "StableDiffusionMixin", + ] + ) + _import_structure["quantizers"] = ["DiffusersQuantizer"] + _import_structure["schedulers"].extend( + [ + "AmusedScheduler", + "CMStochasticIterativeScheduler", + "CogVideoXDDIMScheduler", + "CogVideoXDPMScheduler", + "DDIMInverseScheduler", + "DDIMParallelScheduler", + "DDIMScheduler", + "DDPMParallelScheduler", + "DDPMScheduler", + "DDPMWuerstchenScheduler", + "DEISMultistepScheduler", + "DPMSolverMultistepInverseScheduler", + "DPMSolverMultistepScheduler", + "DPMSolverSinglestepScheduler", + "EDMDPMSolverMultistepScheduler", + "EDMEulerScheduler", + "EulerAncestralDiscreteScheduler", + "EulerDiscreteScheduler", + "FlowMatchEulerDiscreteScheduler", + "FlowMatchHeunDiscreteScheduler", + "FlowMatchLCMScheduler", + "HeunDiscreteScheduler", + "IPNDMScheduler", + "KarrasVeScheduler", + "KDPM2AncestralDiscreteScheduler", + "KDPM2DiscreteScheduler", + "LCMScheduler", + "PNDMScheduler", + "RePaintScheduler", + "SASolverScheduler", + "SchedulerMixin", + "SCMScheduler", + "ScoreSdeVeScheduler", + "TCDScheduler", + "UnCLIPScheduler", + "UniPCMultistepScheduler", + "VQDiffusionScheduler", + ] + ) + _import_structure["training_utils"] = ["EMAModel"] + +try: + if not (is_torch_available() and is_scipy_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_torch_and_scipy_objects # noqa F403 + + _import_structure["utils.dummy_torch_and_scipy_objects"] = [ + name for name in dir(dummy_torch_and_scipy_objects) if not name.startswith("_") + ] + +else: + _import_structure["schedulers"].extend(["LMSDiscreteScheduler"]) + +try: + if not (is_torch_available() and is_torchsde_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_torch_and_torchsde_objects # noqa F403 + + _import_structure["utils.dummy_torch_and_torchsde_objects"] = [ + name for name in dir(dummy_torch_and_torchsde_objects) if not name.startswith("_") + ] + +else: + _import_structure["schedulers"].extend(["CosineDPMSolverMultistepScheduler", "DPMSolverSDEScheduler"]) + +try: + if not (is_torch_available() and is_transformers_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_torch_and_transformers_objects # noqa F403 + + _import_structure["utils.dummy_torch_and_transformers_objects"] = [ + name for name in dir(dummy_torch_and_transformers_objects) if not name.startswith("_") + ] + +else: + _import_structure["pipelines"].extend( + [ + "AllegroPipeline", + "AltDiffusionImg2ImgPipeline", + "AltDiffusionPipeline", + "AmusedImg2ImgPipeline", + "AmusedInpaintPipeline", + "AmusedPipeline", + "AnimateDiffControlNetPipeline", + "AnimateDiffPAGPipeline", + "AnimateDiffPipeline", + "AnimateDiffSDXLPipeline", + "AnimateDiffSparseControlNetPipeline", + "AnimateDiffVideoToVideoControlNetPipeline", + "AnimateDiffVideoToVideoPipeline", + "AudioLDM2Pipeline", + "AudioLDM2ProjectionModel", + "AudioLDM2UNet2DConditionModel", + "AudioLDMPipeline", + "AuraFlowPipeline", + "BlipDiffusionControlNetPipeline", + "BlipDiffusionPipeline", + "CLIPImageProjection", + "CogVideoXFunControlPipeline", + "CogVideoXImageToVideoPipeline", + "CogVideoXPipeline", + "CogVideoXVideoToVideoPipeline", + "CogView3PlusPipeline", + "CogView4ControlPipeline", + "CogView4Pipeline", + "ConsisIDPipeline", + "CosmosTextToWorldPipeline", + "CosmosVideoToWorldPipeline", + "CycleDiffusionPipeline", + "EasyAnimateControlPipeline", + "EasyAnimateInpaintPipeline", + "EasyAnimatePipeline", + "FluxControlImg2ImgPipeline", + "FluxControlInpaintPipeline", + "FluxControlNetImg2ImgPipeline", + "FluxControlNetInpaintPipeline", + "FluxControlNetPipeline", + "FluxControlPipeline", + "FluxFillPipeline", + "FluxImg2ImgPipeline", + "FluxInpaintPipeline", + "FluxPipeline", + "FluxPriorReduxPipeline", + "HiDreamImagePipeline", + "HunyuanDiTControlNetPipeline", + "HunyuanDiTPAGPipeline", + "HunyuanDiTPipeline", + "HunyuanSkyreelsImageToVideoPipeline", + "HunyuanVideoFramepackPipeline", + "HunyuanVideoImageToVideoPipeline", + "HunyuanVideoPipeline", + "I2VGenXLPipeline", + "IFImg2ImgPipeline", + "IFImg2ImgSuperResolutionPipeline", + "IFInpaintingPipeline", + "IFInpaintingSuperResolutionPipeline", + "IFPipeline", + "IFSuperResolutionPipeline", + "ImageTextPipelineOutput", + "Kandinsky3Img2ImgPipeline", + "Kandinsky3Pipeline", + "KandinskyCombinedPipeline", + "KandinskyImg2ImgCombinedPipeline", + "KandinskyImg2ImgPipeline", + "KandinskyInpaintCombinedPipeline", + "KandinskyInpaintPipeline", + "KandinskyPipeline", + "KandinskyPriorPipeline", + "KandinskyV22CombinedPipeline", + "KandinskyV22ControlnetImg2ImgPipeline", + "KandinskyV22ControlnetPipeline", + "KandinskyV22Img2ImgCombinedPipeline", + "KandinskyV22Img2ImgPipeline", + "KandinskyV22InpaintCombinedPipeline", + "KandinskyV22InpaintPipeline", + "KandinskyV22Pipeline", + "KandinskyV22PriorEmb2EmbPipeline", + "KandinskyV22PriorPipeline", + "LatentConsistencyModelImg2ImgPipeline", + "LatentConsistencyModelPipeline", + "LattePipeline", + "LDMTextToImagePipeline", + "LEditsPPPipelineStableDiffusion", + "LEditsPPPipelineStableDiffusionXL", + "LTXConditionPipeline", + "LTXImageToVideoPipeline", + "LTXLatentUpsamplePipeline", + "LTXPipeline", + "Lumina2Pipeline", + "Lumina2Text2ImgPipeline", + "LuminaPipeline", + "LuminaText2ImgPipeline", + "MarigoldDepthPipeline", + "MarigoldIntrinsicsPipeline", + "MarigoldNormalsPipeline", + "MochiPipeline", + "MusicLDMPipeline", + "OmniGenPipeline", + "PaintByExamplePipeline", + "PIAPipeline", + "PixArtAlphaPipeline", + "PixArtSigmaPAGPipeline", + "PixArtSigmaPipeline", + "ReduxImageEncoder", + "SanaControlNetPipeline", + "SanaPAGPipeline", + "SanaPipeline", + "SanaSprintImg2ImgPipeline", + "SanaSprintPipeline", + "SemanticStableDiffusionPipeline", + "ShapEImg2ImgPipeline", + "ShapEPipeline", + "StableAudioPipeline", + "StableAudioProjectionModel", + "StableCascadeCombinedPipeline", + "StableCascadeDecoderPipeline", + "StableCascadePriorPipeline", + "StableDiffusion3ControlNetInpaintingPipeline", + "StableDiffusion3ControlNetPipeline", + "StableDiffusion3Img2ImgPipeline", + "StableDiffusion3InpaintPipeline", + "StableDiffusion3PAGImg2ImgPipeline", + "StableDiffusion3PAGImg2ImgPipeline", + "StableDiffusion3PAGPipeline", + "StableDiffusion3Pipeline", + "StableDiffusionAdapterPipeline", + "StableDiffusionAttendAndExcitePipeline", + "StableDiffusionControlNetImg2ImgPipeline", + "StableDiffusionControlNetInpaintPipeline", + "StableDiffusionControlNetPAGInpaintPipeline", + "StableDiffusionControlNetPAGPipeline", + "StableDiffusionControlNetPipeline", + "StableDiffusionControlNetXSPipeline", + "StableDiffusionDepth2ImgPipeline", + "StableDiffusionDiffEditPipeline", + "StableDiffusionGLIGENPipeline", + "StableDiffusionGLIGENTextImagePipeline", + "StableDiffusionImageVariationPipeline", + "StableDiffusionImg2ImgPipeline", + "StableDiffusionInpaintPipeline", + "StableDiffusionInpaintPipelineLegacy", + "StableDiffusionInstructPix2PixPipeline", + "StableDiffusionLatentUpscalePipeline", + "StableDiffusionLDM3DPipeline", + "StableDiffusionModelEditingPipeline", + "StableDiffusionPAGImg2ImgPipeline", + "StableDiffusionPAGInpaintPipeline", + "StableDiffusionPAGPipeline", + "StableDiffusionPanoramaPipeline", + "StableDiffusionParadigmsPipeline", + "StableDiffusionPipeline", + "StableDiffusionPipelineSafe", + "StableDiffusionPix2PixZeroPipeline", + "StableDiffusionSAGPipeline", + "StableDiffusionUpscalePipeline", + "StableDiffusionXLAdapterPipeline", + "StableDiffusionXLControlNetImg2ImgPipeline", + "StableDiffusionXLControlNetInpaintPipeline", + "StableDiffusionXLControlNetPAGImg2ImgPipeline", + "StableDiffusionXLControlNetPAGPipeline", + "StableDiffusionXLControlNetPipeline", + "StableDiffusionXLControlNetUnionImg2ImgPipeline", + "StableDiffusionXLControlNetUnionInpaintPipeline", + "StableDiffusionXLControlNetUnionPipeline", + "StableDiffusionXLControlNetXSPipeline", + "StableDiffusionXLImg2ImgPipeline", + "StableDiffusionXLInpaintPipeline", + "StableDiffusionXLInstructPix2PixPipeline", + "StableDiffusionXLPAGImg2ImgPipeline", + "StableDiffusionXLPAGInpaintPipeline", + "StableDiffusionXLPAGPipeline", + "StableDiffusionXLPipeline", + "StableUnCLIPImg2ImgPipeline", + "StableUnCLIPPipeline", + "StableVideoDiffusionPipeline", + "TextToVideoSDPipeline", + "TextToVideoZeroPipeline", + "TextToVideoZeroSDXLPipeline", + "UnCLIPImageVariationPipeline", + "UnCLIPPipeline", + "UniDiffuserModel", + "UniDiffuserPipeline", + "UniDiffuserTextDecoder", + "VersatileDiffusionDualGuidedPipeline", + "VersatileDiffusionImageVariationPipeline", + "VersatileDiffusionPipeline", + "VersatileDiffusionTextToImagePipeline", + "VideoToVideoSDPipeline", + "VisualClozeGenerationPipeline", + "VisualClozePipeline", + "VQDiffusionPipeline", + "WanImageToVideoPipeline", + "WanPipeline", + "WanVideoToVideoPipeline", + "WuerstchenCombinedPipeline", + "WuerstchenDecoderPipeline", + "WuerstchenPriorPipeline", + ] + ) + +try: + if not (is_torch_available() and is_transformers_available() and is_opencv_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_torch_and_transformers_and_opencv_objects # noqa F403 + + _import_structure["utils.dummy_torch_and_transformers_and_opencv_objects"] = [ + name for name in dir(dummy_torch_and_transformers_and_opencv_objects) if not name.startswith("_") + ] + +else: + _import_structure["pipelines"].extend(["ConsisIDPipeline"]) + +try: + if not (is_torch_available() and is_transformers_available() and is_k_diffusion_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_torch_and_transformers_and_k_diffusion_objects # noqa F403 + + _import_structure["utils.dummy_torch_and_transformers_and_k_diffusion_objects"] = [ + name for name in dir(dummy_torch_and_transformers_and_k_diffusion_objects) if not name.startswith("_") + ] + +else: + _import_structure["pipelines"].extend(["StableDiffusionKDiffusionPipeline", "StableDiffusionXLKDiffusionPipeline"]) + +try: + if not (is_torch_available() and is_transformers_available() and is_sentencepiece_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_torch_and_transformers_and_sentencepiece_objects # noqa F403 + + _import_structure["utils.dummy_torch_and_transformers_and_sentencepiece_objects"] = [ + name for name in dir(dummy_torch_and_transformers_and_sentencepiece_objects) if not name.startswith("_") + ] + +else: + _import_structure["pipelines"].extend(["KolorsImg2ImgPipeline", "KolorsPAGPipeline", "KolorsPipeline"]) + +try: + if not (is_torch_available() and is_transformers_available() and is_onnx_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_torch_and_transformers_and_onnx_objects # noqa F403 + + _import_structure["utils.dummy_torch_and_transformers_and_onnx_objects"] = [ + name for name in dir(dummy_torch_and_transformers_and_onnx_objects) if not name.startswith("_") + ] + +else: + _import_structure["pipelines"].extend( + [ + "OnnxStableDiffusionImg2ImgPipeline", + "OnnxStableDiffusionInpaintPipeline", + "OnnxStableDiffusionInpaintPipelineLegacy", + "OnnxStableDiffusionPipeline", + "OnnxStableDiffusionUpscalePipeline", + "StableDiffusionOnnxPipeline", + ] + ) + +try: + if not (is_torch_available() and is_librosa_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_torch_and_librosa_objects # noqa F403 + + _import_structure["utils.dummy_torch_and_librosa_objects"] = [ + name for name in dir(dummy_torch_and_librosa_objects) if not name.startswith("_") + ] + +else: + _import_structure["pipelines"].extend(["AudioDiffusionPipeline", "Mel"]) + +try: + if not (is_transformers_available() and is_torch_available() and is_note_seq_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_transformers_and_torch_and_note_seq_objects # noqa F403 + + _import_structure["utils.dummy_transformers_and_torch_and_note_seq_objects"] = [ + name for name in dir(dummy_transformers_and_torch_and_note_seq_objects) if not name.startswith("_") + ] + + +else: + _import_structure["pipelines"].extend(["SpectrogramDiffusionPipeline"]) + +try: + if not is_flax_available(): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_flax_objects # noqa F403 + + _import_structure["utils.dummy_flax_objects"] = [ + name for name in dir(dummy_flax_objects) if not name.startswith("_") + ] + + +else: + _import_structure["models.controlnets.controlnet_flax"] = ["FlaxControlNetModel"] + _import_structure["models.modeling_flax_utils"] = ["FlaxModelMixin"] + _import_structure["models.unets.unet_2d_condition_flax"] = ["FlaxUNet2DConditionModel"] + _import_structure["models.vae_flax"] = ["FlaxAutoencoderKL"] + _import_structure["pipelines"].extend(["FlaxDiffusionPipeline"]) + _import_structure["schedulers"].extend( + [ + "FlaxDDIMScheduler", + "FlaxDDPMScheduler", + "FlaxDPMSolverMultistepScheduler", + "FlaxEulerDiscreteScheduler", + "FlaxKarrasVeScheduler", + "FlaxLMSDiscreteScheduler", + "FlaxPNDMScheduler", + "FlaxSchedulerMixin", + "FlaxScoreSdeVeScheduler", + ] + ) + + +try: + if not (is_flax_available() and is_transformers_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_flax_and_transformers_objects # noqa F403 + + _import_structure["utils.dummy_flax_and_transformers_objects"] = [ + name for name in dir(dummy_flax_and_transformers_objects) if not name.startswith("_") + ] + + +else: + _import_structure["pipelines"].extend( + [ + "FlaxStableDiffusionControlNetPipeline", + "FlaxStableDiffusionImg2ImgPipeline", + "FlaxStableDiffusionInpaintPipeline", + "FlaxStableDiffusionPipeline", + "FlaxStableDiffusionXLPipeline", + ] + ) + +try: + if not (is_note_seq_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from .utils import dummy_note_seq_objects # noqa F403 + + _import_structure["utils.dummy_note_seq_objects"] = [ + name for name in dir(dummy_note_seq_objects) if not name.startswith("_") + ] + + +else: + _import_structure["pipelines"].extend(["MidiProcessor"]) + +if TYPE_CHECKING or DIFFUSERS_SLOW_IMPORT: + from .configuration_utils import ConfigMixin + + try: + if not is_bitsandbytes_available(): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_bitsandbytes_objects import * + else: + from .quantizers.quantization_config import BitsAndBytesConfig + + try: + if not is_gguf_available(): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_gguf_objects import * + else: + from .quantizers.quantization_config import GGUFQuantizationConfig + + try: + if not is_torchao_available(): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_torchao_objects import * + else: + from .quantizers.quantization_config import TorchAoConfig + + try: + if not is_optimum_quanto_available(): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_optimum_quanto_objects import * + else: + from .quantizers.quantization_config import QuantoConfig + + try: + if not is_onnx_available(): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_onnx_objects import * # noqa F403 + else: + from .pipelines import OnnxRuntimeModel + + try: + if not is_torch_available(): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_pt_objects import * # noqa F403 + else: + from .hooks import ( + FasterCacheConfig, + HookRegistry, + PyramidAttentionBroadcastConfig, + apply_faster_cache, + apply_pyramid_attention_broadcast, + ) + from .models import ( + AllegroTransformer3DModel, + AsymmetricAutoencoderKL, + AuraFlowTransformer2DModel, + AutoencoderDC, + AutoencoderKL, + AutoencoderKLAllegro, + AutoencoderKLCogVideoX, + AutoencoderKLCosmos, + AutoencoderKLHunyuanVideo, + AutoencoderKLLTXVideo, + AutoencoderKLMagvit, + AutoencoderKLMochi, + AutoencoderKLTemporalDecoder, + AutoencoderKLWan, + AutoencoderOobleck, + AutoencoderTiny, + AutoModel, + CacheMixin, + CogVideoXTransformer3DModel, + CogView3PlusTransformer2DModel, + CogView4Transformer2DModel, + ConsisIDTransformer3DModel, + ConsistencyDecoderVAE, + ControlNetModel, + ControlNetUnionModel, + ControlNetXSAdapter, + CosmosTransformer3DModel, + DiTTransformer2DModel, + EasyAnimateTransformer3DModel, + FluxControlNetModel, + FluxMultiControlNetModel, + FluxTransformer2DModel, + HiDreamImageTransformer2DModel, + HunyuanDiT2DControlNetModel, + HunyuanDiT2DModel, + HunyuanDiT2DMultiControlNetModel, + HunyuanVideoFramepackTransformer3DModel, + HunyuanVideoTransformer3DModel, + I2VGenXLUNet, + Kandinsky3UNet, + LatteTransformer3DModel, + LTXVideoTransformer3DModel, + Lumina2Transformer2DModel, + LuminaNextDiT2DModel, + MochiTransformer3DModel, + ModelMixin, + MotionAdapter, + MultiAdapter, + MultiControlNetModel, + OmniGenTransformer2DModel, + PixArtTransformer2DModel, + PriorTransformer, + SanaControlNetModel, + SanaTransformer2DModel, + SD3ControlNetModel, + SD3MultiControlNetModel, + SD3Transformer2DModel, + SparseControlNetModel, + StableAudioDiTModel, + T2IAdapter, + T5FilmDecoder, + Transformer2DModel, + TransformerTemporalModel, + UNet1DModel, + UNet2DConditionModel, + UNet2DModel, + UNet3DConditionModel, + UNetControlNetXSModel, + UNetMotionModel, + UNetSpatioTemporalConditionModel, + UVit2DModel, + VQModel, + WanTransformer3DModel, + ) + from .optimization import ( + get_constant_schedule, + get_constant_schedule_with_warmup, + get_cosine_schedule_with_warmup, + get_cosine_with_hard_restarts_schedule_with_warmup, + get_linear_schedule_with_warmup, + get_polynomial_decay_schedule_with_warmup, + get_scheduler, + ) + from .pipelines import ( + AudioPipelineOutput, + AutoPipelineForImage2Image, + AutoPipelineForInpainting, + AutoPipelineForText2Image, + BlipDiffusionControlNetPipeline, + BlipDiffusionPipeline, + CLIPImageProjection, + ConsistencyModelPipeline, + DanceDiffusionPipeline, + DDIMPipeline, + DDPMPipeline, + DiffusionPipeline, + DiTPipeline, + ImagePipelineOutput, + KarrasVePipeline, + LDMPipeline, + LDMSuperResolutionPipeline, + PNDMPipeline, + RePaintPipeline, + ScoreSdeVePipeline, + StableDiffusionMixin, + ) + from .quantizers import DiffusersQuantizer + from .schedulers import ( + AmusedScheduler, + CMStochasticIterativeScheduler, + CogVideoXDDIMScheduler, + CogVideoXDPMScheduler, + DDIMInverseScheduler, + DDIMParallelScheduler, + DDIMScheduler, + DDPMParallelScheduler, + DDPMScheduler, + DDPMWuerstchenScheduler, + DEISMultistepScheduler, + DPMSolverMultistepInverseScheduler, + DPMSolverMultistepScheduler, + DPMSolverSinglestepScheduler, + EDMDPMSolverMultistepScheduler, + EDMEulerScheduler, + EulerAncestralDiscreteScheduler, + EulerDiscreteScheduler, + FlowMatchEulerDiscreteScheduler, + FlowMatchHeunDiscreteScheduler, + FlowMatchLCMScheduler, + HeunDiscreteScheduler, + IPNDMScheduler, + KarrasVeScheduler, + KDPM2AncestralDiscreteScheduler, + KDPM2DiscreteScheduler, + LCMScheduler, + PNDMScheduler, + RePaintScheduler, + SASolverScheduler, + SchedulerMixin, + SCMScheduler, + ScoreSdeVeScheduler, + TCDScheduler, + UnCLIPScheduler, + UniPCMultistepScheduler, + VQDiffusionScheduler, + ) + from .training_utils import EMAModel + + try: + if not (is_torch_available() and is_scipy_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_torch_and_scipy_objects import * # noqa F403 + else: + from .schedulers import LMSDiscreteScheduler + + try: + if not (is_torch_available() and is_torchsde_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_torch_and_torchsde_objects import * # noqa F403 + else: + from .schedulers import CosineDPMSolverMultistepScheduler, DPMSolverSDEScheduler + + try: + if not (is_torch_available() and is_transformers_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_torch_and_transformers_objects import * # noqa F403 + else: + from .pipelines import ( + AllegroPipeline, + AltDiffusionImg2ImgPipeline, + AltDiffusionPipeline, + AmusedImg2ImgPipeline, + AmusedInpaintPipeline, + AmusedPipeline, + AnimateDiffControlNetPipeline, + AnimateDiffPAGPipeline, + AnimateDiffPipeline, + AnimateDiffSDXLPipeline, + AnimateDiffSparseControlNetPipeline, + AnimateDiffVideoToVideoControlNetPipeline, + AnimateDiffVideoToVideoPipeline, + AudioLDM2Pipeline, + AudioLDM2ProjectionModel, + AudioLDM2UNet2DConditionModel, + AudioLDMPipeline, + AuraFlowPipeline, + CLIPImageProjection, + CogVideoXFunControlPipeline, + CogVideoXImageToVideoPipeline, + CogVideoXPipeline, + CogVideoXVideoToVideoPipeline, + CogView3PlusPipeline, + CogView4ControlPipeline, + CogView4Pipeline, + ConsisIDPipeline, + CosmosTextToWorldPipeline, + CosmosVideoToWorldPipeline, + CycleDiffusionPipeline, + EasyAnimateControlPipeline, + EasyAnimateInpaintPipeline, + EasyAnimatePipeline, + FluxControlImg2ImgPipeline, + FluxControlInpaintPipeline, + FluxControlNetImg2ImgPipeline, + FluxControlNetInpaintPipeline, + FluxControlNetPipeline, + FluxControlPipeline, + FluxFillPipeline, + FluxImg2ImgPipeline, + FluxInpaintPipeline, + FluxPipeline, + FluxPriorReduxPipeline, + HiDreamImagePipeline, + HunyuanDiTControlNetPipeline, + HunyuanDiTPAGPipeline, + HunyuanDiTPipeline, + HunyuanSkyreelsImageToVideoPipeline, + HunyuanVideoFramepackPipeline, + HunyuanVideoImageToVideoPipeline, + HunyuanVideoPipeline, + I2VGenXLPipeline, + IFImg2ImgPipeline, + IFImg2ImgSuperResolutionPipeline, + IFInpaintingPipeline, + IFInpaintingSuperResolutionPipeline, + IFPipeline, + IFSuperResolutionPipeline, + ImageTextPipelineOutput, + Kandinsky3Img2ImgPipeline, + Kandinsky3Pipeline, + KandinskyCombinedPipeline, + KandinskyImg2ImgCombinedPipeline, + KandinskyImg2ImgPipeline, + KandinskyInpaintCombinedPipeline, + KandinskyInpaintPipeline, + KandinskyPipeline, + KandinskyPriorPipeline, + KandinskyV22CombinedPipeline, + KandinskyV22ControlnetImg2ImgPipeline, + KandinskyV22ControlnetPipeline, + KandinskyV22Img2ImgCombinedPipeline, + KandinskyV22Img2ImgPipeline, + KandinskyV22InpaintCombinedPipeline, + KandinskyV22InpaintPipeline, + KandinskyV22Pipeline, + KandinskyV22PriorEmb2EmbPipeline, + KandinskyV22PriorPipeline, + LatentConsistencyModelImg2ImgPipeline, + LatentConsistencyModelPipeline, + LattePipeline, + LDMTextToImagePipeline, + LEditsPPPipelineStableDiffusion, + LEditsPPPipelineStableDiffusionXL, + LTXConditionPipeline, + LTXImageToVideoPipeline, + LTXLatentUpsamplePipeline, + LTXPipeline, + Lumina2Pipeline, + Lumina2Text2ImgPipeline, + LuminaPipeline, + LuminaText2ImgPipeline, + MarigoldDepthPipeline, + MarigoldIntrinsicsPipeline, + MarigoldNormalsPipeline, + MochiPipeline, + MusicLDMPipeline, + OmniGenPipeline, + PaintByExamplePipeline, + PIAPipeline, + PixArtAlphaPipeline, + PixArtSigmaPAGPipeline, + PixArtSigmaPipeline, + ReduxImageEncoder, + SanaControlNetPipeline, + SanaPAGPipeline, + SanaPipeline, + SanaSprintImg2ImgPipeline, + SanaSprintPipeline, + SemanticStableDiffusionPipeline, + ShapEImg2ImgPipeline, + ShapEPipeline, + StableAudioPipeline, + StableAudioProjectionModel, + StableCascadeCombinedPipeline, + StableCascadeDecoderPipeline, + StableCascadePriorPipeline, + StableDiffusion3ControlNetInpaintingPipeline, + StableDiffusion3ControlNetPipeline, + StableDiffusion3Img2ImgPipeline, + StableDiffusion3InpaintPipeline, + StableDiffusion3PAGImg2ImgPipeline, + StableDiffusion3PAGPipeline, + StableDiffusion3Pipeline, + StableDiffusionAdapterPipeline, + StableDiffusionAttendAndExcitePipeline, + StableDiffusionControlNetImg2ImgPipeline, + StableDiffusionControlNetInpaintPipeline, + StableDiffusionControlNetPAGInpaintPipeline, + StableDiffusionControlNetPAGPipeline, + StableDiffusionControlNetPipeline, + StableDiffusionControlNetXSPipeline, + StableDiffusionDepth2ImgPipeline, + StableDiffusionDiffEditPipeline, + StableDiffusionGLIGENPipeline, + StableDiffusionGLIGENTextImagePipeline, + StableDiffusionImageVariationPipeline, + StableDiffusionImg2ImgPipeline, + StableDiffusionInpaintPipeline, + StableDiffusionInpaintPipelineLegacy, + StableDiffusionInstructPix2PixPipeline, + StableDiffusionLatentUpscalePipeline, + StableDiffusionLDM3DPipeline, + StableDiffusionModelEditingPipeline, + StableDiffusionPAGImg2ImgPipeline, + StableDiffusionPAGInpaintPipeline, + StableDiffusionPAGPipeline, + StableDiffusionPanoramaPipeline, + StableDiffusionParadigmsPipeline, + StableDiffusionPipeline, + StableDiffusionPipelineSafe, + StableDiffusionPix2PixZeroPipeline, + StableDiffusionSAGPipeline, + StableDiffusionUpscalePipeline, + StableDiffusionXLAdapterPipeline, + StableDiffusionXLControlNetImg2ImgPipeline, + StableDiffusionXLControlNetInpaintPipeline, + StableDiffusionXLControlNetPAGImg2ImgPipeline, + StableDiffusionXLControlNetPAGPipeline, + StableDiffusionXLControlNetPipeline, + StableDiffusionXLControlNetUnionImg2ImgPipeline, + StableDiffusionXLControlNetUnionInpaintPipeline, + StableDiffusionXLControlNetUnionPipeline, + StableDiffusionXLControlNetXSPipeline, + StableDiffusionXLImg2ImgPipeline, + StableDiffusionXLInpaintPipeline, + StableDiffusionXLInstructPix2PixPipeline, + StableDiffusionXLPAGImg2ImgPipeline, + StableDiffusionXLPAGInpaintPipeline, + StableDiffusionXLPAGPipeline, + StableDiffusionXLPipeline, + StableUnCLIPImg2ImgPipeline, + StableUnCLIPPipeline, + StableVideoDiffusionPipeline, + TextToVideoSDPipeline, + TextToVideoZeroPipeline, + TextToVideoZeroSDXLPipeline, + UnCLIPImageVariationPipeline, + UnCLIPPipeline, + UniDiffuserModel, + UniDiffuserPipeline, + UniDiffuserTextDecoder, + VersatileDiffusionDualGuidedPipeline, + VersatileDiffusionImageVariationPipeline, + VersatileDiffusionPipeline, + VersatileDiffusionTextToImagePipeline, + VideoToVideoSDPipeline, + VisualClozeGenerationPipeline, + VisualClozePipeline, + VQDiffusionPipeline, + WanImageToVideoPipeline, + WanPipeline, + WanVideoToVideoPipeline, + WuerstchenCombinedPipeline, + WuerstchenDecoderPipeline, + WuerstchenPriorPipeline, + ) + + try: + if not (is_torch_available() and is_transformers_available() and is_k_diffusion_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_torch_and_transformers_and_k_diffusion_objects import * # noqa F403 + else: + from .pipelines import StableDiffusionKDiffusionPipeline, StableDiffusionXLKDiffusionPipeline + + try: + if not (is_torch_available() and is_transformers_available() and is_sentencepiece_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_torch_and_transformers_and_sentencepiece_objects import * # noqa F403 + else: + from .pipelines import KolorsImg2ImgPipeline, KolorsPAGPipeline, KolorsPipeline + + try: + if not (is_torch_available() and is_transformers_available() and is_opencv_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_torch_and_transformers_and_opencv_objects import * # noqa F403 + else: + from .pipelines import ConsisIDPipeline + + try: + if not (is_torch_available() and is_transformers_available() and is_onnx_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_torch_and_transformers_and_onnx_objects import * # noqa F403 + else: + from .pipelines import ( + OnnxStableDiffusionImg2ImgPipeline, + OnnxStableDiffusionInpaintPipeline, + OnnxStableDiffusionInpaintPipelineLegacy, + OnnxStableDiffusionPipeline, + OnnxStableDiffusionUpscalePipeline, + StableDiffusionOnnxPipeline, + ) + + try: + if not (is_torch_available() and is_librosa_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_torch_and_librosa_objects import * # noqa F403 + else: + from .pipelines import AudioDiffusionPipeline, Mel + + try: + if not (is_transformers_available() and is_torch_available() and is_note_seq_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_transformers_and_torch_and_note_seq_objects import * # noqa F403 + else: + from .pipelines import SpectrogramDiffusionPipeline + + try: + if not is_flax_available(): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_flax_objects import * # noqa F403 + else: + from .models.controlnets.controlnet_flax import FlaxControlNetModel + from .models.modeling_flax_utils import FlaxModelMixin + from .models.unets.unet_2d_condition_flax import FlaxUNet2DConditionModel + from .models.vae_flax import FlaxAutoencoderKL + from .pipelines import FlaxDiffusionPipeline + from .schedulers import ( + FlaxDDIMScheduler, + FlaxDDPMScheduler, + FlaxDPMSolverMultistepScheduler, + FlaxEulerDiscreteScheduler, + FlaxKarrasVeScheduler, + FlaxLMSDiscreteScheduler, + FlaxPNDMScheduler, + FlaxSchedulerMixin, + FlaxScoreSdeVeScheduler, + ) + + try: + if not (is_flax_available() and is_transformers_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_flax_and_transformers_objects import * # noqa F403 + else: + from .pipelines import ( + FlaxStableDiffusionControlNetPipeline, + FlaxStableDiffusionImg2ImgPipeline, + FlaxStableDiffusionInpaintPipeline, + FlaxStableDiffusionPipeline, + FlaxStableDiffusionXLPipeline, + ) + + try: + if not (is_note_seq_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from .utils.dummy_note_seq_objects import * # noqa F403 + else: + from .pipelines import MidiProcessor + +else: + import sys + + sys.modules[__name__] = _LazyModule( + __name__, + globals()["__file__"], + _import_structure, + module_spec=__spec__, + extra_objects={"__version__": __version__}, + ) diff --git a/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/pipelines/__init__.py b/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/pipelines/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..b00530a669ea0db958492568d5185c860614e83e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/pipelines/__init__.py @@ -0,0 +1,848 @@ +from typing import TYPE_CHECKING + +from ..utils import ( + DIFFUSERS_SLOW_IMPORT, + OptionalDependencyNotAvailable, + _LazyModule, + get_objects_from_module, + is_flax_available, + is_k_diffusion_available, + is_librosa_available, + is_note_seq_available, + is_onnx_available, + is_opencv_available, + is_sentencepiece_available, + is_torch_available, + is_torch_npu_available, + is_transformers_available, +) + + +# These modules contain pipelines from multiple libraries/frameworks +_dummy_objects = {} +_import_structure = { + "controlnet": [], + "controlnet_hunyuandit": [], + "controlnet_sd3": [], + "controlnet_xs": [], + "deprecated": [], + "latent_diffusion": [], + "ledits_pp": [], + "marigold": [], + "pag": [], + "stable_diffusion": [], + "stable_diffusion_xl": [], +} + +try: + if not is_torch_available(): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import dummy_pt_objects # noqa F403 + + _dummy_objects.update(get_objects_from_module(dummy_pt_objects)) +else: + _import_structure["auto_pipeline"] = [ + "AutoPipelineForImage2Image", + "AutoPipelineForInpainting", + "AutoPipelineForText2Image", + ] + _import_structure["consistency_models"] = ["ConsistencyModelPipeline"] + _import_structure["dance_diffusion"] = ["DanceDiffusionPipeline"] + _import_structure["ddim"] = ["DDIMPipeline"] + _import_structure["ddpm"] = ["DDPMPipeline"] + _import_structure["dit"] = ["DiTPipeline"] + _import_structure["latent_diffusion"].extend(["LDMSuperResolutionPipeline"]) + _import_structure["pipeline_utils"] = [ + "AudioPipelineOutput", + "DiffusionPipeline", + "StableDiffusionMixin", + "ImagePipelineOutput", + ] + _import_structure["deprecated"].extend( + [ + "PNDMPipeline", + "LDMPipeline", + "RePaintPipeline", + "ScoreSdeVePipeline", + "KarrasVePipeline", + ] + ) +try: + if not (is_torch_available() and is_librosa_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import dummy_torch_and_librosa_objects # noqa F403 + + _dummy_objects.update(get_objects_from_module(dummy_torch_and_librosa_objects)) +else: + _import_structure["deprecated"].extend(["AudioDiffusionPipeline", "Mel"]) + +try: + if not (is_transformers_available() and is_torch_available() and is_note_seq_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import dummy_transformers_and_torch_and_note_seq_objects # noqa F403 + + _dummy_objects.update(get_objects_from_module(dummy_transformers_and_torch_and_note_seq_objects)) +else: + _import_structure["deprecated"].extend( + [ + "MidiProcessor", + "SpectrogramDiffusionPipeline", + ] + ) + +try: + if not (is_torch_available() and is_transformers_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import dummy_torch_and_transformers_objects # noqa F403 + + _dummy_objects.update(get_objects_from_module(dummy_torch_and_transformers_objects)) +else: + _import_structure["deprecated"].extend( + [ + "VQDiffusionPipeline", + "AltDiffusionPipeline", + "AltDiffusionImg2ImgPipeline", + "CycleDiffusionPipeline", + "StableDiffusionInpaintPipelineLegacy", + "StableDiffusionPix2PixZeroPipeline", + "StableDiffusionParadigmsPipeline", + "StableDiffusionModelEditingPipeline", + "VersatileDiffusionDualGuidedPipeline", + "VersatileDiffusionImageVariationPipeline", + "VersatileDiffusionPipeline", + "VersatileDiffusionTextToImagePipeline", + ] + ) + _import_structure["allegro"] = ["AllegroPipeline"] + _import_structure["amused"] = ["AmusedImg2ImgPipeline", "AmusedInpaintPipeline", "AmusedPipeline"] + _import_structure["animatediff"] = [ + "AnimateDiffPipeline", + "AnimateDiffControlNetPipeline", + "AnimateDiffSDXLPipeline", + "AnimateDiffSparseControlNetPipeline", + "AnimateDiffVideoToVideoPipeline", + "AnimateDiffVideoToVideoControlNetPipeline", + ] + _import_structure["flux"] = [ + "FluxControlPipeline", + "FluxControlInpaintPipeline", + "FluxControlImg2ImgPipeline", + "FluxControlNetPipeline", + "FluxControlNetImg2ImgPipeline", + "FluxControlNetInpaintPipeline", + "FluxImg2ImgPipeline", + "FluxInpaintPipeline", + "FluxPipeline", + "FluxFillPipeline", + "FluxPriorReduxPipeline", + "ReduxImageEncoder", + ] + _import_structure["audioldm"] = ["AudioLDMPipeline"] + _import_structure["audioldm2"] = [ + "AudioLDM2Pipeline", + "AudioLDM2ProjectionModel", + "AudioLDM2UNet2DConditionModel", + ] + _import_structure["blip_diffusion"] = ["BlipDiffusionPipeline"] + _import_structure["cogvideo"] = [ + "CogVideoXPipeline", + "CogVideoXImageToVideoPipeline", + "CogVideoXVideoToVideoPipeline", + "CogVideoXFunControlPipeline", + ] + _import_structure["cogview3"] = ["CogView3PlusPipeline"] + _import_structure["cogview4"] = ["CogView4Pipeline", "CogView4ControlPipeline"] + _import_structure["consisid"] = ["ConsisIDPipeline"] + _import_structure["cosmos"] = ["CosmosTextToWorldPipeline", "CosmosVideoToWorldPipeline"] + _import_structure["controlnet"].extend( + [ + "BlipDiffusionControlNetPipeline", + "StableDiffusionControlNetImg2ImgPipeline", + "StableDiffusionControlNetInpaintPipeline", + "StableDiffusionControlNetPipeline", + "StableDiffusionXLControlNetImg2ImgPipeline", + "StableDiffusionXLControlNetInpaintPipeline", + "StableDiffusionXLControlNetPipeline", + "StableDiffusionXLControlNetUnionPipeline", + "StableDiffusionXLControlNetUnionInpaintPipeline", + "StableDiffusionXLControlNetUnionImg2ImgPipeline", + ] + ) + _import_structure["pag"].extend( + [ + "StableDiffusionControlNetPAGInpaintPipeline", + "AnimateDiffPAGPipeline", + "KolorsPAGPipeline", + "HunyuanDiTPAGPipeline", + "StableDiffusion3PAGPipeline", + "StableDiffusion3PAGImg2ImgPipeline", + "StableDiffusionPAGPipeline", + "StableDiffusionPAGImg2ImgPipeline", + "StableDiffusionPAGInpaintPipeline", + "StableDiffusionControlNetPAGPipeline", + "StableDiffusionXLPAGPipeline", + "StableDiffusionXLPAGInpaintPipeline", + "StableDiffusionXLControlNetPAGImg2ImgPipeline", + "StableDiffusionXLControlNetPAGPipeline", + "StableDiffusionXLPAGImg2ImgPipeline", + "PixArtSigmaPAGPipeline", + "SanaPAGPipeline", + ] + ) + _import_structure["controlnet_xs"].extend( + [ + "StableDiffusionControlNetXSPipeline", + "StableDiffusionXLControlNetXSPipeline", + ] + ) + _import_structure["controlnet_hunyuandit"].extend( + [ + "HunyuanDiTControlNetPipeline", + ] + ) + _import_structure["controlnet_sd3"].extend( + [ + "StableDiffusion3ControlNetPipeline", + "StableDiffusion3ControlNetInpaintingPipeline", + ] + ) + _import_structure["deepfloyd_if"] = [ + "IFImg2ImgPipeline", + "IFImg2ImgSuperResolutionPipeline", + "IFInpaintingPipeline", + "IFInpaintingSuperResolutionPipeline", + "IFPipeline", + "IFSuperResolutionPipeline", + ] + _import_structure["easyanimate"] = [ + "EasyAnimatePipeline", + "EasyAnimateInpaintPipeline", + "EasyAnimateControlPipeline", + ] + _import_structure["hidream_image"] = ["HiDreamImagePipeline"] + _import_structure["hunyuandit"] = ["HunyuanDiTPipeline"] + _import_structure["hunyuan_video"] = [ + "HunyuanVideoPipeline", + "HunyuanSkyreelsImageToVideoPipeline", + "HunyuanVideoImageToVideoPipeline", + "HunyuanVideoFramepackPipeline", + ] + _import_structure["kandinsky"] = [ + "KandinskyCombinedPipeline", + "KandinskyImg2ImgCombinedPipeline", + "KandinskyImg2ImgPipeline", + "KandinskyInpaintCombinedPipeline", + "KandinskyInpaintPipeline", + "KandinskyPipeline", + "KandinskyPriorPipeline", + ] + _import_structure["kandinsky2_2"] = [ + "KandinskyV22CombinedPipeline", + "KandinskyV22ControlnetImg2ImgPipeline", + "KandinskyV22ControlnetPipeline", + "KandinskyV22Img2ImgCombinedPipeline", + "KandinskyV22Img2ImgPipeline", + "KandinskyV22InpaintCombinedPipeline", + "KandinskyV22InpaintPipeline", + "KandinskyV22Pipeline", + "KandinskyV22PriorEmb2EmbPipeline", + "KandinskyV22PriorPipeline", + ] + _import_structure["kandinsky3"] = [ + "Kandinsky3Img2ImgPipeline", + "Kandinsky3Pipeline", + ] + _import_structure["latent_consistency_models"] = [ + "LatentConsistencyModelImg2ImgPipeline", + "LatentConsistencyModelPipeline", + ] + _import_structure["latent_diffusion"].extend(["LDMTextToImagePipeline"]) + _import_structure["ledits_pp"].extend( + [ + "LEditsPPPipelineStableDiffusion", + "LEditsPPPipelineStableDiffusionXL", + ] + ) + _import_structure["latte"] = ["LattePipeline"] + _import_structure["ltx"] = [ + "LTXPipeline", + "LTXImageToVideoPipeline", + "LTXConditionPipeline", + "LTXLatentUpsamplePipeline", + ] + _import_structure["lumina"] = ["LuminaPipeline", "LuminaText2ImgPipeline"] + _import_structure["lumina2"] = ["Lumina2Pipeline", "Lumina2Text2ImgPipeline"] + _import_structure["marigold"].extend( + [ + "MarigoldDepthPipeline", + "MarigoldIntrinsicsPipeline", + "MarigoldNormalsPipeline", + ] + ) + _import_structure["mochi"] = ["MochiPipeline"] + _import_structure["musicldm"] = ["MusicLDMPipeline"] + _import_structure["omnigen"] = ["OmniGenPipeline"] + _import_structure["visualcloze"] = ["VisualClozePipeline", "VisualClozeGenerationPipeline"] + _import_structure["paint_by_example"] = ["PaintByExamplePipeline"] + _import_structure["pia"] = ["PIAPipeline"] + _import_structure["pixart_alpha"] = ["PixArtAlphaPipeline", "PixArtSigmaPipeline"] + _import_structure["sana"] = [ + "SanaPipeline", + "SanaSprintPipeline", + "SanaControlNetPipeline", + "SanaSprintImg2ImgPipeline", + ] + _import_structure["semantic_stable_diffusion"] = ["SemanticStableDiffusionPipeline"] + _import_structure["shap_e"] = ["ShapEImg2ImgPipeline", "ShapEPipeline"] + _import_structure["stable_audio"] = [ + "StableAudioProjectionModel", + "StableAudioPipeline", + ] + _import_structure["stable_cascade"] = [ + "StableCascadeCombinedPipeline", + "StableCascadeDecoderPipeline", + "StableCascadePriorPipeline", + ] + _import_structure["stable_diffusion"].extend( + [ + "CLIPImageProjection", + "StableDiffusionDepth2ImgPipeline", + "StableDiffusionImageVariationPipeline", + "StableDiffusionImg2ImgPipeline", + "StableDiffusionInpaintPipeline", + "StableDiffusionInstructPix2PixPipeline", + "StableDiffusionLatentUpscalePipeline", + "StableDiffusionPipeline", + "StableDiffusionUpscalePipeline", + "StableUnCLIPImg2ImgPipeline", + "StableUnCLIPPipeline", + "StableDiffusionLDM3DPipeline", + ] + ) + _import_structure["aura_flow"] = ["AuraFlowPipeline"] + _import_structure["stable_diffusion_3"] = [ + "StableDiffusion3Pipeline", + "StableDiffusion3Img2ImgPipeline", + "StableDiffusion3InpaintPipeline", + ] + _import_structure["stable_diffusion_attend_and_excite"] = ["StableDiffusionAttendAndExcitePipeline"] + _import_structure["stable_diffusion_safe"] = ["StableDiffusionPipelineSafe"] + _import_structure["stable_diffusion_sag"] = ["StableDiffusionSAGPipeline"] + _import_structure["stable_diffusion_gligen"] = [ + "StableDiffusionGLIGENPipeline", + "StableDiffusionGLIGENTextImagePipeline", + ] + _import_structure["stable_video_diffusion"] = ["StableVideoDiffusionPipeline"] + _import_structure["stable_diffusion_xl"].extend( + [ + "StableDiffusionXLImg2ImgPipeline", + "StableDiffusionXLInpaintPipeline", + "StableDiffusionXLInstructPix2PixPipeline", + "StableDiffusionXLPipeline", + ] + ) + _import_structure["stable_diffusion_diffedit"] = ["StableDiffusionDiffEditPipeline"] + _import_structure["stable_diffusion_ldm3d"] = ["StableDiffusionLDM3DPipeline"] + _import_structure["stable_diffusion_panorama"] = ["StableDiffusionPanoramaPipeline"] + _import_structure["t2i_adapter"] = [ + "StableDiffusionAdapterPipeline", + "StableDiffusionXLAdapterPipeline", + ] + _import_structure["text_to_video_synthesis"] = [ + "TextToVideoSDPipeline", + "TextToVideoZeroPipeline", + "TextToVideoZeroSDXLPipeline", + "VideoToVideoSDPipeline", + ] + _import_structure["i2vgen_xl"] = ["I2VGenXLPipeline"] + _import_structure["unclip"] = ["UnCLIPImageVariationPipeline", "UnCLIPPipeline"] + _import_structure["unidiffuser"] = [ + "ImageTextPipelineOutput", + "UniDiffuserModel", + "UniDiffuserPipeline", + "UniDiffuserTextDecoder", + ] + _import_structure["wuerstchen"] = [ + "WuerstchenCombinedPipeline", + "WuerstchenDecoderPipeline", + "WuerstchenPriorPipeline", + ] + _import_structure["wan"] = ["WanPipeline", "WanImageToVideoPipeline", "WanVideoToVideoPipeline"] +try: + if not is_onnx_available(): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import dummy_onnx_objects # noqa F403 + + _dummy_objects.update(get_objects_from_module(dummy_onnx_objects)) +else: + _import_structure["onnx_utils"] = ["OnnxRuntimeModel"] +try: + if not (is_torch_available() and is_transformers_available() and is_onnx_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import dummy_torch_and_transformers_and_onnx_objects # noqa F403 + + _dummy_objects.update(get_objects_from_module(dummy_torch_and_transformers_and_onnx_objects)) +else: + _import_structure["stable_diffusion"].extend( + [ + "OnnxStableDiffusionImg2ImgPipeline", + "OnnxStableDiffusionInpaintPipeline", + "OnnxStableDiffusionPipeline", + "OnnxStableDiffusionUpscalePipeline", + "StableDiffusionOnnxPipeline", + ] + ) + +try: + if not (is_torch_available() and is_transformers_available() and is_k_diffusion_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import ( + dummy_torch_and_transformers_and_k_diffusion_objects, + ) + + _dummy_objects.update(get_objects_from_module(dummy_torch_and_transformers_and_k_diffusion_objects)) +else: + _import_structure["stable_diffusion_k_diffusion"] = [ + "StableDiffusionKDiffusionPipeline", + "StableDiffusionXLKDiffusionPipeline", + ] + +try: + if not (is_torch_available() and is_transformers_available() and is_sentencepiece_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import ( + dummy_torch_and_transformers_and_sentencepiece_objects, + ) + + _dummy_objects.update(get_objects_from_module(dummy_torch_and_transformers_and_sentencepiece_objects)) +else: + _import_structure["kolors"] = [ + "KolorsPipeline", + "KolorsImg2ImgPipeline", + ] + +try: + if not (is_torch_available() and is_transformers_available() and is_opencv_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import ( + dummy_torch_and_transformers_and_opencv_objects, + ) + + _dummy_objects.update(get_objects_from_module(dummy_torch_and_transformers_and_opencv_objects)) +else: + _import_structure["consisid"] = ["ConsisIDPipeline"] + +try: + if not is_flax_available(): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import dummy_flax_objects # noqa F403 + + _dummy_objects.update(get_objects_from_module(dummy_flax_objects)) +else: + _import_structure["pipeline_flax_utils"] = ["FlaxDiffusionPipeline"] +try: + if not (is_flax_available() and is_transformers_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ..utils import dummy_flax_and_transformers_objects # noqa F403 + + _dummy_objects.update(get_objects_from_module(dummy_flax_and_transformers_objects)) +else: + _import_structure["controlnet"].extend(["FlaxStableDiffusionControlNetPipeline"]) + _import_structure["stable_diffusion"].extend( + [ + "FlaxStableDiffusionImg2ImgPipeline", + "FlaxStableDiffusionInpaintPipeline", + "FlaxStableDiffusionPipeline", + ] + ) + _import_structure["stable_diffusion_xl"].extend( + [ + "FlaxStableDiffusionXLPipeline", + ] + ) + +if TYPE_CHECKING or DIFFUSERS_SLOW_IMPORT: + try: + if not is_torch_available(): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_pt_objects import * # noqa F403 + + else: + from .auto_pipeline import ( + AutoPipelineForImage2Image, + AutoPipelineForInpainting, + AutoPipelineForText2Image, + ) + from .consistency_models import ConsistencyModelPipeline + from .dance_diffusion import DanceDiffusionPipeline + from .ddim import DDIMPipeline + from .ddpm import DDPMPipeline + from .deprecated import KarrasVePipeline, LDMPipeline, PNDMPipeline, RePaintPipeline, ScoreSdeVePipeline + from .dit import DiTPipeline + from .latent_diffusion import LDMSuperResolutionPipeline + from .pipeline_utils import ( + AudioPipelineOutput, + DiffusionPipeline, + ImagePipelineOutput, + StableDiffusionMixin, + ) + + try: + if not (is_torch_available() and is_librosa_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_torch_and_librosa_objects import * + else: + from .deprecated import AudioDiffusionPipeline, Mel + + try: + if not (is_torch_available() and is_transformers_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_torch_and_transformers_objects import * + else: + from .allegro import AllegroPipeline + from .amused import AmusedImg2ImgPipeline, AmusedInpaintPipeline, AmusedPipeline + from .animatediff import ( + AnimateDiffControlNetPipeline, + AnimateDiffPipeline, + AnimateDiffSDXLPipeline, + AnimateDiffSparseControlNetPipeline, + AnimateDiffVideoToVideoControlNetPipeline, + AnimateDiffVideoToVideoPipeline, + ) + from .audioldm import AudioLDMPipeline + from .audioldm2 import ( + AudioLDM2Pipeline, + AudioLDM2ProjectionModel, + AudioLDM2UNet2DConditionModel, + ) + from .aura_flow import AuraFlowPipeline + from .blip_diffusion import BlipDiffusionPipeline + from .cogvideo import ( + CogVideoXFunControlPipeline, + CogVideoXImageToVideoPipeline, + CogVideoXPipeline, + CogVideoXVideoToVideoPipeline, + ) + from .cogview3 import CogView3PlusPipeline + from .cogview4 import CogView4ControlPipeline, CogView4Pipeline + from .controlnet import ( + BlipDiffusionControlNetPipeline, + StableDiffusionControlNetImg2ImgPipeline, + StableDiffusionControlNetInpaintPipeline, + StableDiffusionControlNetPipeline, + StableDiffusionXLControlNetImg2ImgPipeline, + StableDiffusionXLControlNetInpaintPipeline, + StableDiffusionXLControlNetPipeline, + StableDiffusionXLControlNetUnionImg2ImgPipeline, + StableDiffusionXLControlNetUnionInpaintPipeline, + StableDiffusionXLControlNetUnionPipeline, + ) + from .controlnet_hunyuandit import ( + HunyuanDiTControlNetPipeline, + ) + from .controlnet_sd3 import StableDiffusion3ControlNetInpaintingPipeline, StableDiffusion3ControlNetPipeline + from .controlnet_xs import ( + StableDiffusionControlNetXSPipeline, + StableDiffusionXLControlNetXSPipeline, + ) + from .cosmos import CosmosTextToWorldPipeline, CosmosVideoToWorldPipeline + from .deepfloyd_if import ( + IFImg2ImgPipeline, + IFImg2ImgSuperResolutionPipeline, + IFInpaintingPipeline, + IFInpaintingSuperResolutionPipeline, + IFPipeline, + IFSuperResolutionPipeline, + ) + from .deprecated import ( + AltDiffusionImg2ImgPipeline, + AltDiffusionPipeline, + CycleDiffusionPipeline, + StableDiffusionInpaintPipelineLegacy, + StableDiffusionModelEditingPipeline, + StableDiffusionParadigmsPipeline, + StableDiffusionPix2PixZeroPipeline, + VersatileDiffusionDualGuidedPipeline, + VersatileDiffusionImageVariationPipeline, + VersatileDiffusionPipeline, + VersatileDiffusionTextToImagePipeline, + VQDiffusionPipeline, + ) + from .easyanimate import ( + EasyAnimateControlPipeline, + EasyAnimateInpaintPipeline, + EasyAnimatePipeline, + ) + from .flux import ( + FluxControlImg2ImgPipeline, + FluxControlInpaintPipeline, + FluxControlNetImg2ImgPipeline, + FluxControlNetInpaintPipeline, + FluxControlNetPipeline, + FluxControlPipeline, + FluxFillPipeline, + FluxImg2ImgPipeline, + FluxInpaintPipeline, + FluxPipeline, + FluxPriorReduxPipeline, + ReduxImageEncoder, + ) + from .hidream_image import HiDreamImagePipeline + from .hunyuan_video import ( + HunyuanSkyreelsImageToVideoPipeline, + HunyuanVideoFramepackPipeline, + HunyuanVideoImageToVideoPipeline, + HunyuanVideoPipeline, + ) + from .hunyuandit import HunyuanDiTPipeline + from .i2vgen_xl import I2VGenXLPipeline + from .kandinsky import ( + KandinskyCombinedPipeline, + KandinskyImg2ImgCombinedPipeline, + KandinskyImg2ImgPipeline, + KandinskyInpaintCombinedPipeline, + KandinskyInpaintPipeline, + KandinskyPipeline, + KandinskyPriorPipeline, + ) + from .kandinsky2_2 import ( + KandinskyV22CombinedPipeline, + KandinskyV22ControlnetImg2ImgPipeline, + KandinskyV22ControlnetPipeline, + KandinskyV22Img2ImgCombinedPipeline, + KandinskyV22Img2ImgPipeline, + KandinskyV22InpaintCombinedPipeline, + KandinskyV22InpaintPipeline, + KandinskyV22Pipeline, + KandinskyV22PriorEmb2EmbPipeline, + KandinskyV22PriorPipeline, + ) + from .kandinsky3 import ( + Kandinsky3Img2ImgPipeline, + Kandinsky3Pipeline, + ) + from .latent_consistency_models import ( + LatentConsistencyModelImg2ImgPipeline, + LatentConsistencyModelPipeline, + ) + from .latent_diffusion import LDMTextToImagePipeline + from .latte import LattePipeline + from .ledits_pp import ( + LEditsPPDiffusionPipelineOutput, + LEditsPPInversionPipelineOutput, + LEditsPPPipelineStableDiffusion, + LEditsPPPipelineStableDiffusionXL, + ) + from .ltx import LTXConditionPipeline, LTXImageToVideoPipeline, LTXLatentUpsamplePipeline, LTXPipeline + from .lumina import LuminaPipeline, LuminaText2ImgPipeline + from .lumina2 import Lumina2Pipeline, Lumina2Text2ImgPipeline + from .marigold import ( + MarigoldDepthPipeline, + MarigoldIntrinsicsPipeline, + MarigoldNormalsPipeline, + ) + from .mochi import MochiPipeline + from .musicldm import MusicLDMPipeline + from .omnigen import OmniGenPipeline + from .pag import ( + AnimateDiffPAGPipeline, + HunyuanDiTPAGPipeline, + KolorsPAGPipeline, + PixArtSigmaPAGPipeline, + SanaPAGPipeline, + StableDiffusion3PAGImg2ImgPipeline, + StableDiffusion3PAGPipeline, + StableDiffusionControlNetPAGInpaintPipeline, + StableDiffusionControlNetPAGPipeline, + StableDiffusionPAGImg2ImgPipeline, + StableDiffusionPAGInpaintPipeline, + StableDiffusionPAGPipeline, + StableDiffusionXLControlNetPAGImg2ImgPipeline, + StableDiffusionXLControlNetPAGPipeline, + StableDiffusionXLPAGImg2ImgPipeline, + StableDiffusionXLPAGInpaintPipeline, + StableDiffusionXLPAGPipeline, + ) + from .paint_by_example import PaintByExamplePipeline + from .pia import PIAPipeline + from .pixart_alpha import PixArtAlphaPipeline, PixArtSigmaPipeline + from .sana import SanaControlNetPipeline, SanaPipeline, SanaSprintImg2ImgPipeline, SanaSprintPipeline + from .semantic_stable_diffusion import SemanticStableDiffusionPipeline + from .shap_e import ShapEImg2ImgPipeline, ShapEPipeline + from .stable_audio import StableAudioPipeline, StableAudioProjectionModel + from .stable_cascade import ( + StableCascadeCombinedPipeline, + StableCascadeDecoderPipeline, + StableCascadePriorPipeline, + ) + from .stable_diffusion import ( + CLIPImageProjection, + StableDiffusionDepth2ImgPipeline, + StableDiffusionImageVariationPipeline, + StableDiffusionImg2ImgPipeline, + StableDiffusionInpaintPipeline, + StableDiffusionInstructPix2PixPipeline, + StableDiffusionLatentUpscalePipeline, + StableDiffusionPipeline, + StableDiffusionUpscalePipeline, + StableUnCLIPImg2ImgPipeline, + StableUnCLIPPipeline, + ) + from .stable_diffusion_3 import ( + StableDiffusion3Img2ImgPipeline, + StableDiffusion3InpaintPipeline, + StableDiffusion3Pipeline, + ) + from .stable_diffusion_attend_and_excite import StableDiffusionAttendAndExcitePipeline + from .stable_diffusion_diffedit import StableDiffusionDiffEditPipeline + from .stable_diffusion_gligen import StableDiffusionGLIGENPipeline, StableDiffusionGLIGENTextImagePipeline + from .stable_diffusion_ldm3d import StableDiffusionLDM3DPipeline + from .stable_diffusion_panorama import StableDiffusionPanoramaPipeline + from .stable_diffusion_safe import StableDiffusionPipelineSafe + from .stable_diffusion_sag import StableDiffusionSAGPipeline + from .stable_diffusion_xl import ( + StableDiffusionXLImg2ImgPipeline, + StableDiffusionXLInpaintPipeline, + StableDiffusionXLInstructPix2PixPipeline, + StableDiffusionXLPipeline, + ) + from .stable_video_diffusion import StableVideoDiffusionPipeline + from .t2i_adapter import ( + StableDiffusionAdapterPipeline, + StableDiffusionXLAdapterPipeline, + ) + from .text_to_video_synthesis import ( + TextToVideoSDPipeline, + TextToVideoZeroPipeline, + TextToVideoZeroSDXLPipeline, + VideoToVideoSDPipeline, + ) + from .unclip import UnCLIPImageVariationPipeline, UnCLIPPipeline + from .unidiffuser import ( + ImageTextPipelineOutput, + UniDiffuserModel, + UniDiffuserPipeline, + UniDiffuserTextDecoder, + ) + from .visualcloze import VisualClozeGenerationPipeline, VisualClozePipeline + from .wan import WanImageToVideoPipeline, WanPipeline, WanVideoToVideoPipeline + from .wuerstchen import ( + WuerstchenCombinedPipeline, + WuerstchenDecoderPipeline, + WuerstchenPriorPipeline, + ) + + try: + if not is_onnx_available(): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_onnx_objects import * # noqa F403 + + else: + from .onnx_utils import OnnxRuntimeModel + + try: + if not (is_torch_available() and is_transformers_available() and is_onnx_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_torch_and_transformers_and_onnx_objects import * + else: + from .stable_diffusion import ( + OnnxStableDiffusionImg2ImgPipeline, + OnnxStableDiffusionInpaintPipeline, + OnnxStableDiffusionPipeline, + OnnxStableDiffusionUpscalePipeline, + StableDiffusionOnnxPipeline, + ) + + try: + if not (is_torch_available() and is_transformers_available() and is_k_diffusion_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_torch_and_transformers_and_k_diffusion_objects import * + else: + from .stable_diffusion_k_diffusion import ( + StableDiffusionKDiffusionPipeline, + StableDiffusionXLKDiffusionPipeline, + ) + + try: + if not (is_torch_available() and is_transformers_available() and is_sentencepiece_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_torch_and_transformers_and_sentencepiece_objects import * + else: + from .kolors import ( + KolorsImg2ImgPipeline, + KolorsPipeline, + ) + + try: + if not (is_torch_available() and is_transformers_available() and is_opencv_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_torch_and_transformers_and_opencv_objects import * + else: + from .consisid import ConsisIDPipeline + + try: + if not is_flax_available(): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_flax_objects import * # noqa F403 + else: + from .pipeline_flax_utils import FlaxDiffusionPipeline + + try: + if not (is_flax_available() and is_transformers_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_flax_and_transformers_objects import * + else: + from .controlnet import FlaxStableDiffusionControlNetPipeline + from .stable_diffusion import ( + FlaxStableDiffusionImg2ImgPipeline, + FlaxStableDiffusionInpaintPipeline, + FlaxStableDiffusionPipeline, + ) + from .stable_diffusion_xl import ( + FlaxStableDiffusionXLPipeline, + ) + + try: + if not (is_transformers_available() and is_torch_available() and is_note_seq_available()): + raise OptionalDependencyNotAvailable() + except OptionalDependencyNotAvailable: + from ..utils.dummy_transformers_and_torch_and_note_seq_objects import * # noqa F403 + + else: + from .deprecated import ( + MidiProcessor, + SpectrogramDiffusionPipeline, + ) + +else: + import sys + + sys.modules[__name__] = _LazyModule( + __name__, + globals()["__file__"], + _import_structure, + module_spec=__spec__, + ) + for name, value in _dummy_objects.items(): + setattr(sys.modules[__name__], name, value) diff --git a/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/pipelines/sana/__init__.py b/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/pipelines/sana/__init__.py new file mode 100644 index 0000000000000000000000000000000000000000..91684f35f153516de83cd65ebed28164970b7548 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/pipelines/sana/__init__.py @@ -0,0 +1,53 @@ +from typing import TYPE_CHECKING + +from ...utils import ( + DIFFUSERS_SLOW_IMPORT, + OptionalDependencyNotAvailable, + _LazyModule, + get_objects_from_module, + is_torch_available, + is_transformers_available, +) + + +_dummy_objects = {} +_import_structure = {} + + +try: + if not (is_transformers_available() and is_torch_available()): + raise OptionalDependencyNotAvailable() +except OptionalDependencyNotAvailable: + from ...utils import dummy_torch_and_transformers_objects # noqa F403 + + _dummy_objects.update(get_objects_from_module(dummy_torch_and_transformers_objects)) +else: + _import_structure["pipeline_sana"] = ["SanaPipeline"] + _import_structure["pipeline_sana_controlnet"] = ["SanaControlNetPipeline"] + _import_structure["pipeline_sana_sprint"] = ["SanaSprintPipeline"] + _import_structure["pipeline_sana_sprint_img2img"] = ["SanaSprintImg2ImgPipeline"] + +if TYPE_CHECKING or DIFFUSERS_SLOW_IMPORT: + try: + if not (is_transformers_available() and is_torch_available()): + raise OptionalDependencyNotAvailable() + + except OptionalDependencyNotAvailable: + from ...utils.dummy_torch_and_transformers_objects import * + else: + from .pipeline_sana import SanaPipeline + from .pipeline_sana_controlnet import SanaControlNetPipeline + from .pipeline_sana_sprint import SanaSprintPipeline + from .pipeline_sana_sprint_img2img import SanaSprintImg2ImgPipeline +else: + import sys + + sys.modules[__name__] = _LazyModule( + __name__, + globals()["__file__"], + _import_structure, + module_spec=__spec__, + ) + + for name, value in _dummy_objects.items(): + setattr(sys.modules[__name__], name, value) diff --git a/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/pipelines/sana/pipeline_sana_sprint_img2img.py b/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/pipelines/sana/pipeline_sana_sprint_img2img.py new file mode 100644 index 0000000000000000000000000000000000000000..f71b980ffc84360e9a510621e9a5aeca91a6c4e8 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/pipelines/sana/pipeline_sana_sprint_img2img.py @@ -0,0 +1,975 @@ +# Copyright 2024 PixArt-Sigma Authors and The HuggingFace Team. All rights reserved. +# +# Licensed under the Apache License, Version 2.0 (the "License"); +# you may not use this file except in compliance with the License. +# You may obtain a copy of the License at +# +# http://www.apache.org/licenses/LICENSE-2.0 +# +# Unless required by applicable law or agreed to in writing, software +# distributed under the License is distributed on an "AS IS" BASIS, +# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. +# See the License for the specific language governing permissions and +# limitations under the License. + +import html +import inspect +import re +import urllib.parse as ul +import warnings +from typing import Any, Callable, Dict, List, Optional, Tuple, Union + +import torch +import torch.nn.functional as F +from transformers import Gemma2PreTrainedModel, GemmaTokenizer, GemmaTokenizerFast + +from ...callbacks import MultiPipelineCallbacks, PipelineCallback +from ...image_processor import PipelineImageInput, PixArtImageProcessor +from ...loaders import SanaLoraLoaderMixin +from ...models import AutoencoderDC, SanaTransformer2DModel +from ...schedulers import DPMSolverMultistepScheduler +from ...utils import ( + BACKENDS_MAPPING, + USE_PEFT_BACKEND, + is_bs4_available, + is_ftfy_available, + is_torch_xla_available, + logging, + replace_example_docstring, + scale_lora_layers, + unscale_lora_layers, +) +from ...utils.torch_utils import randn_tensor +from ..pipeline_utils import DiffusionPipeline +from ..pixart_alpha.pipeline_pixart_alpha import ASPECT_RATIO_1024_BIN +from .pipeline_output import SanaPipelineOutput + + +if is_torch_xla_available(): + import torch_xla.core.xla_model as xm + + XLA_AVAILABLE = True +else: + XLA_AVAILABLE = False + +logger = logging.get_logger(__name__) # pylint: disable=invalid-name + +if is_bs4_available(): + from bs4 import BeautifulSoup + +if is_ftfy_available(): + import ftfy + +EXAMPLE_DOC_STRING = """ + Examples: + ```py + >>> import torch + >>> from diffusers import SanaSprintImg2ImgPipeline + >>> from diffusers.utils.loading_utils import load_image + + >>> pipe = SanaSprintImg2ImgPipeline.from_pretrained( + ... "Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers", torch_dtype=torch.bfloat16 + ... ) + >>> pipe.to("cuda") + + >>> image = load_image( + ... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/penguin.png" + ... ) + + + >>> image = pipe(prompt="a cute pink bear", image=image, strength=0.5, height=832, width=480).images[0] + >>> image[0].save("output.png") + ``` +""" + + +# Copied from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion.retrieve_timesteps +def retrieve_timesteps( + scheduler, + num_inference_steps: Optional[int] = None, + device: Optional[Union[str, torch.device]] = None, + timesteps: Optional[List[int]] = None, + sigmas: Optional[List[float]] = None, + **kwargs, +): + r""" + Calls the scheduler's `set_timesteps` method and retrieves timesteps from the scheduler after the call. Handles + custom timesteps. Any kwargs will be supplied to `scheduler.set_timesteps`. + + Args: + scheduler (`SchedulerMixin`): + The scheduler to get timesteps from. + num_inference_steps (`int`): + The number of diffusion steps used when generating samples with a pre-trained model. If used, `timesteps` + must be `None`. + device (`str` or `torch.device`, *optional*): + The device to which the timesteps should be moved to. If `None`, the timesteps are not moved. + timesteps (`List[int]`, *optional*): + Custom timesteps used to override the timestep spacing strategy of the scheduler. If `timesteps` is passed, + `num_inference_steps` and `sigmas` must be `None`. + sigmas (`List[float]`, *optional*): + Custom sigmas used to override the timestep spacing strategy of the scheduler. If `sigmas` is passed, + `num_inference_steps` and `timesteps` must be `None`. + + Returns: + `Tuple[torch.Tensor, int]`: A tuple where the first element is the timestep schedule from the scheduler and the + second element is the number of inference steps. + """ + if timesteps is not None and sigmas is not None: + raise ValueError("Only one of `timesteps` or `sigmas` can be passed. Please choose one to set custom values") + if timesteps is not None: + accepts_timesteps = "timesteps" in set(inspect.signature(scheduler.set_timesteps).parameters.keys()) + if not accepts_timesteps: + raise ValueError( + f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom" + f" timestep schedules. Please check whether you are using the correct scheduler." + ) + scheduler.set_timesteps(timesteps=timesteps, device=device, **kwargs) + timesteps = scheduler.timesteps + num_inference_steps = len(timesteps) + elif sigmas is not None: + accept_sigmas = "sigmas" in set(inspect.signature(scheduler.set_timesteps).parameters.keys()) + if not accept_sigmas: + raise ValueError( + f"The current scheduler class {scheduler.__class__}'s `set_timesteps` does not support custom" + f" sigmas schedules. Please check whether you are using the correct scheduler." + ) + scheduler.set_timesteps(sigmas=sigmas, device=device, **kwargs) + timesteps = scheduler.timesteps + num_inference_steps = len(timesteps) + else: + scheduler.set_timesteps(num_inference_steps, device=device, **kwargs) + timesteps = scheduler.timesteps + return timesteps, num_inference_steps + + +class SanaSprintImg2ImgPipeline(DiffusionPipeline, SanaLoraLoaderMixin): + r""" + Pipeline for text-to-image generation using [SANA-Sprint](https://huggingface.co/papers/2503.09641). + """ + + # fmt: off + bad_punct_regex = re.compile( + r"[" + "#®•©™&@·º½¾¿¡§~" + r"\)" + r"\(" + r"\]" + r"\[" + r"\}" + r"\{" + r"\|" + "\\" + r"\/" + r"\*" + r"]{1,}") + # fmt: on + + model_cpu_offload_seq = "text_encoder->transformer->vae" + _callback_tensor_inputs = ["latents", "prompt_embeds"] + + def __init__( + self, + tokenizer: Union[GemmaTokenizer, GemmaTokenizerFast], + text_encoder: Gemma2PreTrainedModel, + vae: AutoencoderDC, + transformer: SanaTransformer2DModel, + scheduler: DPMSolverMultistepScheduler, + ): + super().__init__() + + self.register_modules( + tokenizer=tokenizer, text_encoder=text_encoder, vae=vae, transformer=transformer, scheduler=scheduler + ) + + self.vae_scale_factor = ( + 2 ** (len(self.vae.config.encoder_block_out_channels) - 1) + if hasattr(self, "vae") and self.vae is not None + else 32 + ) + self.image_processor = PixArtImageProcessor(vae_scale_factor=self.vae_scale_factor) + + # Copied from diffusers.pipelines.sana.pipeline_sana.SanaPipeline.enable_vae_slicing + def enable_vae_slicing(self): + r""" + Enable sliced VAE decoding. When this option is enabled, the VAE will split the input tensor in slices to + compute decoding in several steps. This is useful to save some memory and allow larger batch sizes. + """ + self.vae.enable_slicing() + + # Copied from diffusers.pipelines.sana.pipeline_sana.SanaPipeline.disable_vae_slicing + def disable_vae_slicing(self): + r""" + Disable sliced VAE decoding. If `enable_vae_slicing` was previously enabled, this method will go back to + computing decoding in one step. + """ + self.vae.disable_slicing() + + # Copied from diffusers.pipelines.sana.pipeline_sana.SanaPipeline.enable_vae_tiling + def enable_vae_tiling(self): + r""" + Enable tiled VAE decoding. When this option is enabled, the VAE will split the input tensor into tiles to + compute decoding and encoding in several steps. This is useful for saving a large amount of memory and to allow + processing larger images. + """ + self.vae.enable_tiling() + + def disable_vae_tiling(self): + r""" + Disable tiled VAE decoding. If `enable_vae_tiling` was previously enabled, this method will go back to + computing decoding in one step. + """ + self.vae.disable_tiling() + + # Copied from diffusers.pipelines.sana.pipeline_sana.SanaPipeline._get_gemma_prompt_embeds + def _get_gemma_prompt_embeds( + self, + prompt: Union[str, List[str]], + device: torch.device, + dtype: torch.dtype, + clean_caption: bool = False, + max_sequence_length: int = 300, + complex_human_instruction: Optional[List[str]] = None, + ): + r""" + Encodes the prompt into text encoder hidden states. + + Args: + prompt (`str` or `List[str]`, *optional*): + prompt to be encoded + device: (`torch.device`, *optional*): + torch device to place the resulting embeddings on + clean_caption (`bool`, defaults to `False`): + If `True`, the function will preprocess and clean the provided caption before encoding. + max_sequence_length (`int`, defaults to 300): Maximum sequence length to use for the prompt. + complex_human_instruction (`list[str]`, defaults to `complex_human_instruction`): + If `complex_human_instruction` is not empty, the function will use the complex Human instruction for + the prompt. + """ + prompt = [prompt] if isinstance(prompt, str) else prompt + + if getattr(self, "tokenizer", None) is not None: + self.tokenizer.padding_side = "right" + + prompt = self._text_preprocessing(prompt, clean_caption=clean_caption) + + # prepare complex human instruction + if not complex_human_instruction: + max_length_all = max_sequence_length + else: + chi_prompt = "\n".join(complex_human_instruction) + prompt = [chi_prompt + p for p in prompt] + num_chi_prompt_tokens = len(self.tokenizer.encode(chi_prompt)) + max_length_all = num_chi_prompt_tokens + max_sequence_length - 2 + + text_inputs = self.tokenizer( + prompt, + padding="max_length", + max_length=max_length_all, + truncation=True, + add_special_tokens=True, + return_tensors="pt", + ) + text_input_ids = text_inputs.input_ids + + prompt_attention_mask = text_inputs.attention_mask + prompt_attention_mask = prompt_attention_mask.to(device) + + prompt_embeds = self.text_encoder(text_input_ids.to(device), attention_mask=prompt_attention_mask) + prompt_embeds = prompt_embeds[0].to(dtype=dtype, device=device) + + return prompt_embeds, prompt_attention_mask + + # Copied from diffusers.pipelines.sana.pipeline_sana_sprint.SanaSprintPipeline.encode_prompt + def encode_prompt( + self, + prompt: Union[str, List[str]], + num_images_per_prompt: int = 1, + device: Optional[torch.device] = None, + prompt_embeds: Optional[torch.Tensor] = None, + prompt_attention_mask: Optional[torch.Tensor] = None, + clean_caption: bool = False, + max_sequence_length: int = 300, + complex_human_instruction: Optional[List[str]] = None, + lora_scale: Optional[float] = None, + ): + r""" + Encodes the prompt into text encoder hidden states. + + Args: + prompt (`str` or `List[str]`, *optional*): + prompt to be encoded + + num_images_per_prompt (`int`, *optional*, defaults to 1): + number of images that should be generated per prompt + device: (`torch.device`, *optional*): + torch device to place the resulting embeddings on + prompt_embeds (`torch.Tensor`, *optional*): + Pre-generated text embeddings. Can be used to easily tweak text inputs, *e.g.* prompt weighting. If not + provided, text embeddings will be generated from `prompt` input argument. + clean_caption (`bool`, defaults to `False`): + If `True`, the function will preprocess and clean the provided caption before encoding. + max_sequence_length (`int`, defaults to 300): Maximum sequence length to use for the prompt. + complex_human_instruction (`list[str]`, defaults to `complex_human_instruction`): + If `complex_human_instruction` is not empty, the function will use the complex Human instruction for + the prompt. + """ + + if device is None: + device = self._execution_device + + if self.text_encoder is not None: + dtype = self.text_encoder.dtype + else: + dtype = None + + # set lora scale so that monkey patched LoRA + # function of text encoder can correctly access it + if lora_scale is not None and isinstance(self, SanaLoraLoaderMixin): + self._lora_scale = lora_scale + + # dynamically adjust the LoRA scale + if self.text_encoder is not None and USE_PEFT_BACKEND: + scale_lora_layers(self.text_encoder, lora_scale) + + if getattr(self, "tokenizer", None) is not None: + self.tokenizer.padding_side = "right" + + # See Section 3.1. of the paper. + max_length = max_sequence_length + select_index = [0] + list(range(-max_length + 1, 0)) + + if prompt_embeds is None: + prompt_embeds, prompt_attention_mask = self._get_gemma_prompt_embeds( + prompt=prompt, + device=device, + dtype=dtype, + clean_caption=clean_caption, + max_sequence_length=max_sequence_length, + complex_human_instruction=complex_human_instruction, + ) + + prompt_embeds = prompt_embeds[:, select_index] + prompt_attention_mask = prompt_attention_mask[:, select_index] + + bs_embed, seq_len, _ = prompt_embeds.shape + # duplicate text embeddings and attention mask for each generation per prompt, using mps friendly method + prompt_embeds = prompt_embeds.repeat(1, num_images_per_prompt, 1) + prompt_embeds = prompt_embeds.view(bs_embed * num_images_per_prompt, seq_len, -1) + prompt_attention_mask = prompt_attention_mask.view(bs_embed, -1) + prompt_attention_mask = prompt_attention_mask.repeat(num_images_per_prompt, 1) + + if self.text_encoder is not None: + if isinstance(self, SanaLoraLoaderMixin) and USE_PEFT_BACKEND: + # Retrieve the original scale by scaling back the LoRA layers + unscale_lora_layers(self.text_encoder, lora_scale) + + return prompt_embeds, prompt_attention_mask + + # Copied from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion.StableDiffusionPipeline.prepare_extra_step_kwargs + def prepare_extra_step_kwargs(self, generator, eta): + # prepare extra kwargs for the scheduler step, since not all schedulers have the same signature + # eta (η) is only used with the DDIMScheduler, it will be ignored for other schedulers. + # eta corresponds to η in DDIM paper: https://huggingface.co/papers/2010.02502 + # and should be between [0, 1] + + accepts_eta = "eta" in set(inspect.signature(self.scheduler.step).parameters.keys()) + extra_step_kwargs = {} + if accepts_eta: + extra_step_kwargs["eta"] = eta + + # check if the scheduler accepts generator + accepts_generator = "generator" in set(inspect.signature(self.scheduler.step).parameters.keys()) + if accepts_generator: + extra_step_kwargs["generator"] = generator + return extra_step_kwargs + + # Copied from diffusers.pipelines.stable_diffusion_3.pipeline_stable_diffusion_3_img2img.StableDiffusion3Img2ImgPipeline.get_timesteps + def get_timesteps(self, num_inference_steps, strength, device): + # get the original timestep using init_timestep + init_timestep = min(num_inference_steps * strength, num_inference_steps) + + t_start = int(max(num_inference_steps - init_timestep, 0)) + timesteps = self.scheduler.timesteps[t_start * self.scheduler.order :] + if hasattr(self.scheduler, "set_begin_index"): + self.scheduler.set_begin_index(t_start * self.scheduler.order) + + return timesteps, num_inference_steps - t_start + + def check_inputs( + self, + prompt, + strength, + height, + width, + num_inference_steps, + timesteps, + max_timesteps, + intermediate_timesteps, + callback_on_step_end_tensor_inputs=None, + prompt_embeds=None, + prompt_attention_mask=None, + ): + if strength < 0 or strength > 1: + raise ValueError(f"The value of strength should in [0.0, 1.0] but is {strength}") + + if height % 32 != 0 or width % 32 != 0: + raise ValueError(f"`height` and `width` have to be divisible by 32 but are {height} and {width}.") + + if callback_on_step_end_tensor_inputs is not None and not all( + k in self._callback_tensor_inputs for k in callback_on_step_end_tensor_inputs + ): + raise ValueError( + f"`callback_on_step_end_tensor_inputs` has to be in {self._callback_tensor_inputs}, but found {[k for k in callback_on_step_end_tensor_inputs if k not in self._callback_tensor_inputs]}" + ) + + if prompt is not None and prompt_embeds is not None: + raise ValueError( + f"Cannot forward both `prompt`: {prompt} and `prompt_embeds`: {prompt_embeds}. Please make sure to" + " only forward one of the two." + ) + elif prompt is None and prompt_embeds is None: + raise ValueError( + "Provide either `prompt` or `prompt_embeds`. Cannot leave both `prompt` and `prompt_embeds` undefined." + ) + elif prompt is not None and (not isinstance(prompt, str) and not isinstance(prompt, list)): + raise ValueError(f"`prompt` has to be of type `str` or `list` but is {type(prompt)}") + + if prompt_embeds is not None and prompt_attention_mask is None: + raise ValueError("Must provide `prompt_attention_mask` when specifying `prompt_embeds`.") + + if timesteps is not None and len(timesteps) != num_inference_steps + 1: + raise ValueError("If providing custom timesteps, `timesteps` must be of length `num_inference_steps + 1`.") + + if timesteps is not None and max_timesteps is not None: + raise ValueError("If providing custom timesteps, `max_timesteps` should not be provided.") + + if timesteps is None and max_timesteps is None: + raise ValueError("Should provide either `timesteps` or `max_timesteps`.") + + if intermediate_timesteps is not None and num_inference_steps != 2: + raise ValueError("Intermediate timesteps for SCM is not supported when num_inference_steps != 2.") + + # Copied from diffusers.pipelines.deepfloyd_if.pipeline_if.IFPipeline._text_preprocessing + def _text_preprocessing(self, text, clean_caption=False): + if clean_caption and not is_bs4_available(): + logger.warning(BACKENDS_MAPPING["bs4"][-1].format("Setting `clean_caption=True`")) + logger.warning("Setting `clean_caption` to False...") + clean_caption = False + + if clean_caption and not is_ftfy_available(): + logger.warning(BACKENDS_MAPPING["ftfy"][-1].format("Setting `clean_caption=True`")) + logger.warning("Setting `clean_caption` to False...") + clean_caption = False + + if not isinstance(text, (tuple, list)): + text = [text] + + def process(text: str): + if clean_caption: + text = self._clean_caption(text) + text = self._clean_caption(text) + else: + text = text.lower().strip() + return text + + return [process(t) for t in text] + + # Copied from diffusers.pipelines.deepfloyd_if.pipeline_if.IFPipeline._clean_caption + def _clean_caption(self, caption): + caption = str(caption) + caption = ul.unquote_plus(caption) + caption = caption.strip().lower() + caption = re.sub("", "person", caption) + # urls: + caption = re.sub( + r"\b((?:https?:(?:\/{1,3}|[a-zA-Z0-9%])|[a-zA-Z0-9.\-]+[.](?:com|co|ru|net|org|edu|gov|it)[\w/-]*\b\/?(?!@)))", # noqa + "", + caption, + ) # regex for urls + caption = re.sub( + r"\b((?:www:(?:\/{1,3}|[a-zA-Z0-9%])|[a-zA-Z0-9.\-]+[.](?:com|co|ru|net|org|edu|gov|it)[\w/-]*\b\/?(?!@)))", # noqa + "", + caption, + ) # regex for urls + # html: + caption = BeautifulSoup(caption, features="html.parser").text + + # @ + caption = re.sub(r"@[\w\d]+\b", "", caption) + + # 31C0—31EF CJK Strokes + # 31F0—31FF Katakana Phonetic Extensions + # 3200—32FF Enclosed CJK Letters and Months + # 3300—33FF CJK Compatibility + # 3400—4DBF CJK Unified Ideographs Extension A + # 4DC0—4DFF Yijing Hexagram Symbols + # 4E00—9FFF CJK Unified Ideographs + caption = re.sub(r"[\u31c0-\u31ef]+", "", caption) + caption = re.sub(r"[\u31f0-\u31ff]+", "", caption) + caption = re.sub(r"[\u3200-\u32ff]+", "", caption) + caption = re.sub(r"[\u3300-\u33ff]+", "", caption) + caption = re.sub(r"[\u3400-\u4dbf]+", "", caption) + caption = re.sub(r"[\u4dc0-\u4dff]+", "", caption) + caption = re.sub(r"[\u4e00-\u9fff]+", "", caption) + ####################################################### + + # все виды тире / all types of dash --> "-" + caption = re.sub( + r"[\u002D\u058A\u05BE\u1400\u1806\u2010-\u2015\u2E17\u2E1A\u2E3A\u2E3B\u2E40\u301C\u3030\u30A0\uFE31\uFE32\uFE58\uFE63\uFF0D]+", # noqa + "-", + caption, + ) + + # кавычки к одному стандарту + caption = re.sub(r"[`´«»“”¨]", '"', caption) + caption = re.sub(r"[‘’]", "'", caption) + + # " + caption = re.sub(r""?", "", caption) + # & + caption = re.sub(r"&", "", caption) + + # ip addresses: + caption = re.sub(r"\d{1,3}\.\d{1,3}\.\d{1,3}\.\d{1,3}", " ", caption) + + # article ids: + caption = re.sub(r"\d:\d\d\s+$", "", caption) + + # \n + caption = re.sub(r"\\n", " ", caption) + + # "#123" + caption = re.sub(r"#\d{1,3}\b", "", caption) + # "#12345.." + caption = re.sub(r"#\d{5,}\b", "", caption) + # "123456.." + caption = re.sub(r"\b\d{6,}\b", "", caption) + # filenames: + caption = re.sub(r"[\S]+\.(?:png|jpg|jpeg|bmp|webp|eps|pdf|apk|mp4)", "", caption) + + # + caption = re.sub(r"[\"\']{2,}", r'"', caption) # """AUSVERKAUFT""" + caption = re.sub(r"[\.]{2,}", r" ", caption) # """AUSVERKAUFT""" + + caption = re.sub(self.bad_punct_regex, r" ", caption) # ***AUSVERKAUFT***, #AUSVERKAUFT + caption = re.sub(r"\s+\.\s+", r" ", caption) # " . " + + # this-is-my-cute-cat / this_is_my_cute_cat + regex2 = re.compile(r"(?:\-|\_)") + if len(re.findall(regex2, caption)) > 3: + caption = re.sub(regex2, " ", caption) + + caption = ftfy.fix_text(caption) + caption = html.unescape(html.unescape(caption)) + + caption = re.sub(r"\b[a-zA-Z]{1,3}\d{3,15}\b", "", caption) # jc6640 + caption = re.sub(r"\b[a-zA-Z]+\d+[a-zA-Z]+\b", "", caption) # jc6640vc + caption = re.sub(r"\b\d+[a-zA-Z]+\d+\b", "", caption) # 6640vc231 + + caption = re.sub(r"(worldwide\s+)?(free\s+)?shipping", "", caption) + caption = re.sub(r"(free\s)?download(\sfree)?", "", caption) + caption = re.sub(r"\bclick\b\s(?:for|on)\s\w+", "", caption) + caption = re.sub(r"\b(?:png|jpg|jpeg|bmp|webp|eps|pdf|apk|mp4)(\simage[s]?)?", "", caption) + caption = re.sub(r"\bpage\s+\d+\b", "", caption) + + caption = re.sub(r"\b\d*[a-zA-Z]+\d+[a-zA-Z]+\d+[a-zA-Z\d]*\b", r" ", caption) # j2d1a2a... + + caption = re.sub(r"\b\d+\.?\d*[xх×]\d+\.?\d*\b", "", caption) + + caption = re.sub(r"\b\s+\:\s+", r": ", caption) + caption = re.sub(r"(\D[,\./])\b", r"\1 ", caption) + caption = re.sub(r"\s+", " ", caption) + + caption.strip() + + caption = re.sub(r"^[\"\']([\w\W]+)[\"\']$", r"\1", caption) + caption = re.sub(r"^[\'\_,\-\:;]", r"", caption) + caption = re.sub(r"[\'\_,\-\:\-\+]$", r"", caption) + caption = re.sub(r"^\.\S+$", "", caption) + + return caption.strip() + + def prepare_image( + self, + image: PipelineImageInput, + width: int, + height: int, + device: torch.device, + dtype: torch.dtype, + ): + if isinstance(image, torch.Tensor): + if image.ndim == 3: + image = image.unsqueeze(0) + # Resize if current dimensions do not match target dimensions. + if image.shape[2] != height or image.shape[3] != width: + image = F.interpolate(image, size=(height, width), mode="bilinear", align_corners=False) + + image = self.image_processor.preprocess(image, height=height, width=width) + + else: + image = self.image_processor.preprocess(image, height=height, width=width) + + image = image.to(device=device, dtype=dtype) + + return image + + def prepare_latents( + self, image, timestep, batch_size, num_channels_latents, height, width, dtype, device, generator, latents=None + ): + if latents is not None: + return latents.to(device=device, dtype=dtype) + + shape = ( + batch_size, + num_channels_latents, + int(height) // self.vae_scale_factor, + int(width) // self.vae_scale_factor, + ) + + if image.shape[1] != num_channels_latents: + image = self.vae.encode(image).latent + image_latents = image * self.vae.config.scaling_factor * self.scheduler.config.sigma_data + else: + image_latents = image + if batch_size > image_latents.shape[0] and batch_size % image_latents.shape[0] == 0: + # expand init_latents for batch_size + additional_image_per_prompt = batch_size // image_latents.shape[0] + image_latents = torch.cat([image_latents] * additional_image_per_prompt, dim=0) + elif batch_size > image_latents.shape[0] and batch_size % image_latents.shape[0] != 0: + raise ValueError( + f"Cannot duplicate `image` of batch size {image_latents.shape[0]} to {batch_size} text prompts." + ) + else: + image_latents = torch.cat([image_latents], dim=0) + + if isinstance(generator, list) and len(generator) != batch_size: + raise ValueError( + f"You have passed a list of generators of length {len(generator)}, but requested an effective batch" + f" size of {batch_size}. Make sure the batch size matches the length of the generators." + ) + + # adapt from https://github.com/huggingface/diffusers/blob/c36f8487df35895421c15f351c7d360bd680[…]/examples/research_projects/sana/train_sana_sprint_diffusers.py + noise = randn_tensor(shape, generator=generator, device=device, dtype=dtype) * self.scheduler.config.sigma_data + latents = torch.cos(timestep) * image_latents + torch.sin(timestep) * noise + return latents + + @property + def guidance_scale(self): + return self._guidance_scale + + @property + def attention_kwargs(self): + return self._attention_kwargs + + @property + def num_timesteps(self): + return self._num_timesteps + + @property + def interrupt(self): + return self._interrupt + + @torch.no_grad() + @replace_example_docstring(EXAMPLE_DOC_STRING) + def __call__( + self, + prompt: Union[str, List[str]] = None, + num_inference_steps: int = 2, + timesteps: List[int] = None, + max_timesteps: float = 1.57080, + intermediate_timesteps: float = 1.3, + guidance_scale: float = 4.5, + image: PipelineImageInput = None, + strength: float = 0.6, + num_images_per_prompt: Optional[int] = 1, + height: int = 1024, + width: int = 1024, + eta: float = 0.0, + generator: Optional[Union[torch.Generator, List[torch.Generator]]] = None, + latents: Optional[torch.Tensor] = None, + prompt_embeds: Optional[torch.Tensor] = None, + prompt_attention_mask: Optional[torch.Tensor] = None, + output_type: Optional[str] = "pil", + return_dict: bool = True, + clean_caption: bool = False, + use_resolution_binning: bool = True, + attention_kwargs: Optional[Dict[str, Any]] = None, + callback_on_step_end: Optional[Callable[[int, int, Dict], None]] = None, + callback_on_step_end_tensor_inputs: List[str] = ["latents"], + max_sequence_length: int = 300, + complex_human_instruction: List[str] = [ + "Given a user prompt, generate an 'Enhanced prompt' that provides detailed visual descriptions suitable for image generation. Evaluate the level of detail in the user prompt:", + "- If the prompt is simple, focus on adding specifics about colors, shapes, sizes, textures, and spatial relationships to create vivid and concrete scenes.", + "- If the prompt is already detailed, refine and enhance the existing details slightly without overcomplicating.", + "Here are examples of how to transform or refine prompts:", + "- User Prompt: A cat sleeping -> Enhanced: A small, fluffy white cat curled up in a round shape, sleeping peacefully on a warm sunny windowsill, surrounded by pots of blooming red flowers.", + "- User Prompt: A busy city street -> Enhanced: A bustling city street scene at dusk, featuring glowing street lamps, a diverse crowd of people in colorful clothing, and a double-decker bus passing by towering glass skyscrapers.", + "Please generate only the enhanced description for the prompt below and avoid including any additional commentary or evaluations:", + "User Prompt: ", + ], + ) -> Union[SanaPipelineOutput, Tuple]: + """ + Function invoked when calling the pipeline for generation. + + Args: + prompt (`str` or `List[str]`, *optional*): + The prompt or prompts to guide the image generation. If not defined, one has to pass `prompt_embeds`. + instead. + num_inference_steps (`int`, *optional*, defaults to 20): + The number of denoising steps. More denoising steps usually lead to a higher quality image at the + expense of slower inference. + max_timesteps (`float`, *optional*, defaults to 1.57080): + The maximum timestep value used in the SCM scheduler. + intermediate_timesteps (`float`, *optional*, defaults to 1.3): + The intermediate timestep value used in SCM scheduler (only used when num_inference_steps=2). + timesteps (`List[int]`, *optional*): + Custom timesteps to use for the denoising process with schedulers which support a `timesteps` argument + in their `set_timesteps` method. If not defined, the default behavior when `num_inference_steps` is + passed will be used. Must be in descending order. + guidance_scale (`float`, *optional*, defaults to 4.5): + Guidance scale as defined in [Classifier-Free Diffusion Guidance](https://arxiv.org/abs/2207.12598). + `guidance_scale` is defined as `w` of equation 2. of [Imagen + Paper](https://arxiv.org/pdf/2205.11487.pdf). Guidance scale is enabled by setting `guidance_scale > + 1`. Higher guidance scale encourages to generate images that are closely linked to the text `prompt`, + usually at the expense of lower image quality. + num_images_per_prompt (`int`, *optional*, defaults to 1): + The number of images to generate per prompt. + height (`int`, *optional*, defaults to self.unet.config.sample_size): + The height in pixels of the generated image. + width (`int`, *optional*, defaults to self.unet.config.sample_size): + The width in pixels of the generated image. + eta (`float`, *optional*, defaults to 0.0): + Corresponds to parameter eta (η) in the DDIM paper: https://arxiv.org/abs/2010.02502. Only applies to + [`schedulers.DDIMScheduler`], will be ignored for others. + generator (`torch.Generator` or `List[torch.Generator]`, *optional*): + One or a list of [torch generator(s)](https://pytorch.org/docs/stable/generated/torch.Generator.html) + to make generation deterministic. + latents (`torch.Tensor`, *optional*): + Pre-generated noisy latents, sampled from a Gaussian distribution, to be used as inputs for image + generation. Can be used to tweak the same generation with different prompts. If not provided, a latents + tensor will ge generated by sampling using the supplied random `generator`. + prompt_embeds (`torch.Tensor`, *optional*): + Pre-generated text embeddings. Can be used to easily tweak text inputs, *e.g.* prompt weighting. If not + provided, text embeddings will be generated from `prompt` input argument. + prompt_attention_mask (`torch.Tensor`, *optional*): Pre-generated attention mask for text embeddings. + output_type (`str`, *optional*, defaults to `"pil"`): + The output format of the generate image. Choose between + [PIL](https://pillow.readthedocs.io/en/stable/): `PIL.Image.Image` or `np.array`. + return_dict (`bool`, *optional*, defaults to `True`): + Whether or not to return a [`~pipelines.stable_diffusion.IFPipelineOutput`] instead of a plain tuple. + attention_kwargs: + A kwargs dictionary that if specified is passed along to the `AttentionProcessor` as defined under + `self.processor` in + [diffusers.models.attention_processor](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention_processor.py). + clean_caption (`bool`, *optional*, defaults to `True`): + Whether or not to clean the caption before creating embeddings. Requires `beautifulsoup4` and `ftfy` to + be installed. If the dependencies are not installed, the embeddings will be created from the raw + prompt. + use_resolution_binning (`bool` defaults to `True`): + If set to `True`, the requested height and width are first mapped to the closest resolutions using + `ASPECT_RATIO_1024_BIN`. After the produced latents are decoded into images, they are resized back to + the requested resolution. Useful for generating non-square images. + callback_on_step_end (`Callable`, *optional*): + A function that calls at the end of each denoising steps during the inference. The function is called + with the following arguments: `callback_on_step_end(self: DiffusionPipeline, step: int, timestep: int, + callback_kwargs: Dict)`. `callback_kwargs` will include a list of all tensors as specified by + `callback_on_step_end_tensor_inputs`. + callback_on_step_end_tensor_inputs (`List`, *optional*): + The list of tensor inputs for the `callback_on_step_end` function. The tensors specified in the list + will be passed as `callback_kwargs` argument. You will only be able to include variables listed in the + `._callback_tensor_inputs` attribute of your pipeline class. + max_sequence_length (`int` defaults to `300`): + Maximum sequence length to use with the `prompt`. + complex_human_instruction (`List[str]`, *optional*): + Instructions for complex human attention: + https://github.com/NVlabs/Sana/blob/main/configs/sana_app_config/Sana_1600M_app.yaml#L55. + + Examples: + + Returns: + [`~pipelines.sana.pipeline_output.SanaPipelineOutput`] or `tuple`: + If `return_dict` is `True`, [`~pipelines.sana.pipeline_output.SanaPipelineOutput`] is returned, + otherwise a `tuple` is returned where the first element is a list with the generated images + """ + + if isinstance(callback_on_step_end, (PipelineCallback, MultiPipelineCallbacks)): + callback_on_step_end_tensor_inputs = callback_on_step_end.tensor_inputs + + # 1. Check inputs. Raise error if not correct + if use_resolution_binning: + if self.transformer.config.sample_size == 32: + aspect_ratio_bin = ASPECT_RATIO_1024_BIN + else: + raise ValueError("Invalid sample size") + orig_height, orig_width = height, width + height, width = self.image_processor.classify_height_width_bin(height, width, ratios=aspect_ratio_bin) + + self.check_inputs( + prompt=prompt, + strength=strength, + height=height, + width=width, + num_inference_steps=num_inference_steps, + timesteps=timesteps, + max_timesteps=max_timesteps, + intermediate_timesteps=intermediate_timesteps, + callback_on_step_end_tensor_inputs=callback_on_step_end_tensor_inputs, + prompt_embeds=prompt_embeds, + prompt_attention_mask=prompt_attention_mask, + ) + + self._guidance_scale = guidance_scale + self._attention_kwargs = attention_kwargs + self._interrupt = False + + # 2. Default height and width to transformer + if prompt is not None and isinstance(prompt, str): + batch_size = 1 + elif prompt is not None and isinstance(prompt, list): + batch_size = len(prompt) + else: + batch_size = prompt_embeds.shape[0] + + device = self._execution_device + lora_scale = self.attention_kwargs.get("scale", None) if self.attention_kwargs is not None else None + + # 2. Preprocess image + init_image = self.prepare_image(image, width, height, device, self.vae.dtype) + + # 3. Encode input prompt + ( + prompt_embeds, + prompt_attention_mask, + ) = self.encode_prompt( + prompt, + num_images_per_prompt=num_images_per_prompt, + device=device, + prompt_embeds=prompt_embeds, + prompt_attention_mask=prompt_attention_mask, + clean_caption=clean_caption, + max_sequence_length=max_sequence_length, + complex_human_instruction=complex_human_instruction, + lora_scale=lora_scale, + ) + + # 5. Prepare timesteps + timesteps, num_inference_steps = retrieve_timesteps( + self.scheduler, + num_inference_steps, + device, + timesteps, + sigmas=None, + max_timesteps=max_timesteps, + intermediate_timesteps=intermediate_timesteps, + ) + if hasattr(self.scheduler, "set_begin_index"): + self.scheduler.set_begin_index(0) + + timesteps, num_inference_steps = self.get_timesteps(num_inference_steps, strength, device) + if num_inference_steps < 1: + raise ValueError( + f"After adjusting the num_inference_steps by strength parameter: {strength}, the number of pipeline" + f"steps is {num_inference_steps} which is < 1 and not appropriate for this pipeline." + ) + latent_timestep = timesteps[:1] + + # 5. Prepare latents. + latent_channels = self.transformer.config.in_channels + latents = self.prepare_latents( + init_image, + latent_timestep, + batch_size * num_images_per_prompt, + latent_channels, + height, + width, + torch.float32, + device, + generator, + latents, + ) + + # I think this is redundant given the scaling in prepare_latents + # latents = latents * self.scheduler.config.sigma_data + + guidance = torch.full([1], guidance_scale, device=device, dtype=torch.float32) + guidance = guidance.expand(latents.shape[0]).to(prompt_embeds.dtype) + guidance = guidance * self.transformer.config.guidance_embeds_scale + + # 6. Prepare extra step kwargs. TODO: Logic should ideally just be moved out of the pipeline + extra_step_kwargs = self.prepare_extra_step_kwargs(generator, eta) + + # 7. Denoising loop + timesteps = timesteps[:-1] + num_warmup_steps = max(len(timesteps) - num_inference_steps * self.scheduler.order, 0) + self._num_timesteps = len(timesteps) + + transformer_dtype = self.transformer.dtype + with self.progress_bar(total=num_inference_steps) as progress_bar: + for i, t in enumerate(timesteps): + if self.interrupt: + continue + + # broadcast to batch dimension in a way that's compatible with ONNX/Core ML + timestep = t.expand(latents.shape[0]) + latents_model_input = latents / self.scheduler.config.sigma_data + + scm_timestep = torch.sin(timestep) / (torch.cos(timestep) + torch.sin(timestep)) + + scm_timestep_expanded = scm_timestep.view(-1, 1, 1, 1) + latent_model_input = latents_model_input * torch.sqrt( + scm_timestep_expanded**2 + (1 - scm_timestep_expanded) ** 2 + ) + + # predict noise model_output + noise_pred = self.transformer( + latent_model_input.to(dtype=transformer_dtype), + encoder_hidden_states=prompt_embeds.to(dtype=transformer_dtype), + encoder_attention_mask=prompt_attention_mask, + guidance=guidance, + timestep=scm_timestep, + return_dict=False, + attention_kwargs=self.attention_kwargs, + )[0] + + noise_pred = ( + (1 - 2 * scm_timestep_expanded) * latent_model_input + + (1 - 2 * scm_timestep_expanded + 2 * scm_timestep_expanded**2) * noise_pred + ) / torch.sqrt(scm_timestep_expanded**2 + (1 - scm_timestep_expanded) ** 2) + noise_pred = noise_pred.float() * self.scheduler.config.sigma_data + + # compute previous image: x_t -> x_t-1 + latents, denoised = self.scheduler.step( + noise_pred, timestep, latents, **extra_step_kwargs, return_dict=False + ) + + if callback_on_step_end is not None: + callback_kwargs = {} + for k in callback_on_step_end_tensor_inputs: + callback_kwargs[k] = locals()[k] + callback_outputs = callback_on_step_end(self, i, t, callback_kwargs) + + latents = callback_outputs.pop("latents", latents) + prompt_embeds = callback_outputs.pop("prompt_embeds", prompt_embeds) + + # call the callback, if provided + if i == len(timesteps) - 1 or ((i + 1) > num_warmup_steps and (i + 1) % self.scheduler.order == 0): + progress_bar.update() + + if XLA_AVAILABLE: + xm.mark_step() + + latents = denoised / self.scheduler.config.sigma_data + if output_type == "latent": + image = latents + else: + latents = latents.to(self.vae.dtype) + try: + image = self.vae.decode(latents / self.vae.config.scaling_factor, return_dict=False)[0] + except torch.cuda.OutOfMemoryError as e: + warnings.warn( + f"{e}. \n" + f"Try to use VAE tiling for large images. For example: \n" + f"pipe.vae.enable_tiling(tile_sample_min_width=512, tile_sample_min_height=512)" + ) + if use_resolution_binning: + image = self.image_processor.resize_and_crop_tensor(image, orig_width, orig_height) + + if not output_type == "latent": + image = self.image_processor.postprocess(image, output_type=output_type) + + # Offload all models + self.maybe_free_model_hooks() + + if not return_dict: + return (image,) + + return SanaPipelineOutput(images=image) diff --git a/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/utils/dummy_torch_and_transformers_objects.py b/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/utils/dummy_torch_and_transformers_objects.py new file mode 100644 index 0000000000000000000000000000000000000000..159d81add3550a54e7bcbcd61f417327f3c3a39d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/solution/reference/src/diffusers/utils/dummy_torch_and_transformers_objects.py @@ -0,0 +1,2957 @@ +# This file is autogenerated by the command `make fix-copies`, do not edit. +from ..utils import DummyObject, requires_backends + + +class AllegroPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AltDiffusionImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AltDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AmusedImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AmusedInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AmusedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffSDXLPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffSparseControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffVideoToVideoControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AnimateDiffVideoToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AudioLDM2Pipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AudioLDM2ProjectionModel(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AudioLDM2UNet2DConditionModel(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AudioLDMPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class AuraFlowPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CLIPImageProjection(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogVideoXFunControlPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogVideoXImageToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogVideoXPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogVideoXVideoToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogView3PlusPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogView4ControlPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CogView4Pipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class ConsisIDPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CosmosTextToWorldPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CosmosVideoToWorldPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class CycleDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class EasyAnimateControlPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class EasyAnimateInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class EasyAnimatePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxControlImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxControlInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxControlNetImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxControlNetInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxControlPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxFillPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class FluxPriorReduxPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HiDreamImagePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanDiTControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanDiTPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanDiTPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanSkyreelsImageToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanVideoFramepackPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanVideoImageToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class HunyuanVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class I2VGenXLPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class IFImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class IFImg2ImgSuperResolutionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class IFInpaintingPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class IFInpaintingSuperResolutionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class IFPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class IFSuperResolutionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class ImageTextPipelineOutput(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class Kandinsky3Img2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class Kandinsky3Pipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyImg2ImgCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyInpaintCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyPriorPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22CombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22ControlnetImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22ControlnetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22Img2ImgCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22Img2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22InpaintCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22InpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22Pipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22PriorEmb2EmbPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class KandinskyV22PriorPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LatentConsistencyModelImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LatentConsistencyModelPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LattePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LDMTextToImagePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LEditsPPPipelineStableDiffusion(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LEditsPPPipelineStableDiffusionXL(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LTXConditionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LTXImageToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LTXLatentUpsamplePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LTXPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class Lumina2Pipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class Lumina2Text2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LuminaPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class LuminaText2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class MarigoldDepthPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class MarigoldIntrinsicsPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class MarigoldNormalsPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class MochiPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class MusicLDMPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class OmniGenPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class PaintByExamplePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class PIAPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class PixArtAlphaPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class PixArtSigmaPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class PixArtSigmaPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class ReduxImageEncoder(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class SanaControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class SanaPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class SanaPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class SanaSprintImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class SanaSprintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class SemanticStableDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class ShapEImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class ShapEPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableAudioPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableAudioProjectionModel(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableCascadeCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableCascadeDecoderPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableCascadePriorPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3ControlNetInpaintingPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3ControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3Img2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3InpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3PAGImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3PAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusion3Pipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionAdapterPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionAttendAndExcitePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionControlNetImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionControlNetInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionControlNetPAGInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionControlNetPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionControlNetXSPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionDepth2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionDiffEditPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionGLIGENPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionGLIGENTextImagePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionImageVariationPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionInpaintPipelineLegacy(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionInstructPix2PixPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionLatentUpscalePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionLDM3DPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionModelEditingPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPAGImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPAGInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPanoramaPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionParadigmsPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPipelineSafe(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionPix2PixZeroPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionSAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionUpscalePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLAdapterPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetPAGImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetUnionImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetUnionInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetUnionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLControlNetXSPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLInstructPix2PixPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLPAGImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLPAGInpaintPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLPAGPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableDiffusionXLPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableUnCLIPImg2ImgPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableUnCLIPPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class StableVideoDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class TextToVideoSDPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class TextToVideoZeroPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class TextToVideoZeroSDXLPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class UnCLIPImageVariationPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class UnCLIPPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class UniDiffuserModel(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class UniDiffuserPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class UniDiffuserTextDecoder(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VersatileDiffusionDualGuidedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VersatileDiffusionImageVariationPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VersatileDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VersatileDiffusionTextToImagePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VideoToVideoSDPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VisualClozeGenerationPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VisualClozePipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class VQDiffusionPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class WanImageToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class WanPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class WanVideoToVideoPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class WuerstchenCombinedPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class WuerstchenDecoderPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + +class WuerstchenPriorPipeline(metaclass=DummyObject): + _backends = ["torch", "transformers"] + + def __init__(self, *args, **kwargs): + requires_backends(self, ["torch", "transformers"]) + + @classmethod + def from_config(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) + + @classmethod + def from_pretrained(cls, *args, **kwargs): + requires_backends(cls, ["torch", "transformers"]) diff --git a/tasks/tasksmith-48efdcc71e7d/solution/solve.sh b/tasks/tasksmith-48efdcc71e7d/solution/solve.sh new file mode 100644 index 0000000000000000000000000000000000000000..ff83ed3fe0fdd16ed89d5e133cf27c3d2317f431 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/solution/solve.sh @@ -0,0 +1,12 @@ +#!/bin/sh +set -eu +mkdir -p -- /workspace/src/diffusers +cp /solution/reference/src/diffusers/__init__.py /workspace/src/diffusers/__init__.py +mkdir -p -- /workspace/src/diffusers/pipelines +cp /solution/reference/src/diffusers/pipelines/__init__.py /workspace/src/diffusers/pipelines/__init__.py +mkdir -p -- /workspace/src/diffusers/pipelines/sana +cp /solution/reference/src/diffusers/pipelines/sana/__init__.py /workspace/src/diffusers/pipelines/sana/__init__.py +mkdir -p -- /workspace/src/diffusers/pipelines/sana +cp /solution/reference/src/diffusers/pipelines/sana/pipeline_sana_sprint_img2img.py /workspace/src/diffusers/pipelines/sana/pipeline_sana_sprint_img2img.py +mkdir -p -- /workspace/src/diffusers/utils +cp /solution/reference/src/diffusers/utils/dummy_torch_and_transformers_objects.py /workspace/src/diffusers/utils/dummy_torch_and_transformers_objects.py diff --git a/tasks/tasksmith-48efdcc71e7d/task.toml b/tasks/tasksmith-48efdcc71e7d/task.toml new file mode 100644 index 0000000000000000000000000000000000000000..feacd7c8bb6f4ecb2f6462af9d0fc61c846abd50 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/task.toml @@ -0,0 +1,113 @@ +schema_version = "1.3" + +[task] +name = "repo2rlenv/tasksmith-48efdcc71e7d" + +[metadata.repo2env] +recipe = "tasksmith" +recipe_version = "1" +source_url = "https://github.com/huggingface/diffusers/pull/11602" +source_head = "ec717aa57e11f811e6d1fe950170af57590dab46" +source_base = "a4da216125c29001dc33fefd37f959231bc4bf0a" +workspace_strategy = "head_minus_source_patch" +source_diff_sha256 = "d26a0c792fcfd9546509f1def3098e050b920d158961ca241cdcf12d6482eaed" +acceptance_profile = "practical-generation-v1" +upstream_test_policy = "replace" +reward_kinds = [ + "test_execution", +] +quality_status = "exported" +fail_to_pass_count = 11 +pass_to_pass_count = 1 +bundle_hash = "sha256:9ab4539c81f598dadc9bb6a797c0f1dcdb2f3ead9cfc337ee143fd2112fc7e5e" + +[metadata.repo2env.evaluation] +schema_version = "1" +status = "verified" +stage = "complete" +reason_codes = [ + "quality_verified", +] +detail = "Reviewed controls, semantic probes and blind rollout passed the quality profile." +checked_at = "2026-09-14T05:11:21.307024Z" +provenance = "assisted" +subject_bundle_hash = "sha256:9ab4539c81f598dadc9bb6a797c0f1dcdb2f3ead9cfc337ee143fd2112fc7e5e" +profile = "practical-generation-v1" +source_task_path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-scale50/batch-v9/candidates/1866473e8b52/candidates/48efdcc71e7d/quality/revisions/r0/tasksmith-48efdcc71e7d" +source_task_toml_sha256 = "91a9262dfe1c52493f2bf139114a0745a6ca1f98b16259c6da79ee727e72f586" + +[[metadata.repo2env.evaluation.evidence]] +kind = "quality_result" +path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-scale50/batch-v9/candidates/1866473e8b52/candidates/48efdcc71e7d/quality/result.json" +sha256 = "0fb25aa16d371d122b6cda57d456e4737728d80449f205a07eb3dc9532936168" +subject_bundle_hash = "sha256:9ab4539c81f598dadc9bb6a797c0f1dcdb2f3ead9cfc337ee143fd2112fc7e5e" + +[[metadata.repo2env.evaluation.evidence]] +kind = "baseline" +path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-scale50/batch-v9/candidates/1866473e8b52/candidates/48efdcc71e7d/quality/trials/r0-baseline/tsbatch-1c3a4e1be0c6-1866473e8b52-q-48efdcc7-r0-baseline/tasksmith-48efdcc71e7d__LtrSqWh/result.json" +sha256 = "697fdcce4506c8ced2c3e9af8b8662d60163168e80a29625cd8e90b704efb5cc" +subject_bundle_hash = "sha256:9ab4539c81f598dadc9bb6a797c0f1dcdb2f3ead9cfc337ee143fd2112fc7e5e" +harbor_task_checksum = "241cc69273592d36e657ba56660dee77fd04500c6a801a188dc0da4c19aed28f" + +[[metadata.repo2env.evaluation.evidence]] +kind = "oracle" +path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-scale50/batch-v9/candidates/1866473e8b52/candidates/48efdcc71e7d/quality/trials/r0-oracle/tsbatch-1c3a4e1be0c6-1866473e8b52-q-48efdcc7-r0-oracle/tasksmith-48efdcc71e7d__tNdaL7z/result.json" +sha256 = "731e8759f49ebe7c749bd4c42d96a9a36ed60d0623954bfa6970a81ef4f3f245" +subject_bundle_hash = "sha256:9ab4539c81f598dadc9bb6a797c0f1dcdb2f3ead9cfc337ee143fd2112fc7e5e" +harbor_task_checksum = "241cc69273592d36e657ba56660dee77fd04500c6a801a188dc0da4c19aed28f" + +[[metadata.repo2env.evaluation.evidence]] +kind = "probe" +path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-scale50/batch-v9/candidates/1866473e8b52/candidates/48efdcc71e7d/quality/trials/r0-probe0/tsbatch-1c3a4e1be0c6-1866473e8b52-q-48efdcc7-r0-probe0/tasksmith-48efdcc71e7d__zEzUNvS/result.json" +sha256 = "e2022ffd207af6ebf2715d17f5641627af47d99e3c0840b1dd45103540d6c575" +subject_bundle_hash = "sha256:a6372249d5b0963b99e353e5cfc77331d07e17436cb52b4bde9d923fc08a2d82" +harbor_task_checksum = "34066cfa9bbd78265ad6b5660c78457d79f8e4a12e9668dead685ab8b09fe0df" + +[[metadata.repo2env.evaluation.evidence]] +kind = "probe" +path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-scale50/batch-v9/candidates/1866473e8b52/candidates/48efdcc71e7d/quality/trials/r0-probe1/tsbatch-1c3a4e1be0c6-1866473e8b52-q-48efdcc7-r0-probe1/tasksmith-48efdcc71e7d__T8KYzFJ/result.json" +sha256 = "3b510e5f14d31ef54404dcb56af56c6225e26b76436a2a57a0f3ac8a7a32232d" +subject_bundle_hash = "sha256:c6ee333c1c92e55d36c7817ace36d78ce70209d874e9665f38ef786c32f0afcf" +harbor_task_checksum = "fe21b975e921102a04b45c525023277783d2ae62a4580ebd5bb961d49bd5a711" + +[[metadata.repo2env.evaluation.evidence]] +kind = "rollout" +path = "/Users/adithya/projects/Repo2RLEnv-tasksmith/workspace/tasksmith-scale50/batch-v9/candidates/1866473e8b52/candidates/48efdcc71e7d/quality/trials/r0-rollout/tsbatch-1c3a4e1be0c6-1866473e8b52-q-48efdcc7-r0-rollout/tasksmith-48efdcc71e7d__ajgpLnH/result.json" +sha256 = "2c614d889c8519b4d1a5933fa3c0be3cc498410641a9eaefdfdeec2f8856738e" +subject_bundle_hash = "sha256:9ab4539c81f598dadc9bb6a797c0f1dcdb2f3ead9cfc337ee143fd2112fc7e5e" +harbor_task_checksum = "241cc69273592d36e657ba56660dee77fd04500c6a801a188dc0da4c19aed28f" + +[metadata.repo2env.quality_requirements] +probe_focus = [ + "model_behavior", +] + +[environment] +cpus = 1 +memory_mb = 2048 +build_timeout_sec = 600 +network_mode = "no-network" + +[agent] +timeout_sec = 600 +user = "learner" +network_mode = "no-network" + +[verifier] +timeout_sec = 270 +user = "root" +network_mode = "no-network" +environment_mode = "separate" + +[verifier.environment] +network_mode = "no-network" +cpus = 1 +memory_mb = 2048 + +[[artifacts]] +source = "/workspace/src/diffusers" +exclude = [ + "__pycache__", + "*.pyc", + ".pytest_cache", +] diff --git a/tasks/tasksmith-48efdcc71e7d/tests/Dockerfile b/tasks/tasksmith-48efdcc71e7d/tests/Dockerfile new file mode 100644 index 0000000000000000000000000000000000000000..8671f370eea1f309658ea4e30562c2148d4918f7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/Dockerfile @@ -0,0 +1,12 @@ +FROM python:3.12-slim +WORKDIR /workspace +RUN python -m pip install --no-cache-dir --extra-index-url https://download.pytorch.org/whl/cpu torch==2.11.0+cpu numpy==2.5.3 transformers==4.49.0 tokenizers==0.21.4 huggingface-hub==0.35.3 accelerate==1.4.0 safetensors==0.4.5 sentencepiece==0.2.0 protobuf==3.20.3 pillow==12.3.0 parameterized==0.9.0 pytest==8.4.2 pytest-timeout==2.3.1 packaging==26.3 setuptools==78.1.0 wheel==0.48.0 regex==2024.11.6 requests==2.32.3 requests-mock==1.12.1 filelock==3.13.1 pyyaml==6.0.2 psutil==7.0.0 fsspec==2024.12.0 tqdm==4.67.1 +RUN HF_HUB_OFFLINE=0 TRANSFORMERS_OFFLINE=0 python -c 'exec('"'"'"""Standalone image-build program; never import target models or receive credentials."""\n\nfrom __future__ import annotations\n\nimport hashlib\nimport json\nfrom pathlib import Path\n\n\ndef fetch_assets(assets: list[dict], cache: Path) -> None:\n from huggingface_hub import get_hf_file_metadata, hf_hub_download, hf_hub_url\n\n manifests = []\n for asset in assets:\n sizes = {}\n for filename in asset["filenames"]:\n metadata = get_hf_file_metadata(\n hf_hub_url(asset["repo_id"], filename, revision=asset["revision"]), token=False\n )\n if metadata.commit_hash != asset["revision"] or metadata.size is None:\n raise ValueError("Hub metadata must resolve to the pinned revision and known size")\n sizes[filename] = metadata.size\n if sum(sizes.values()) > asset["max_bytes"]:\n raise ValueError(f"Asset exceeds download allowance: {asset[\'"'"'repo_id\'"'"']}")\n records = []\n for filename, size in sizes.items():\n path = Path(\n hf_hub_download(\n repo_id=asset["repo_id"],\n filename=filename,\n revision=asset["revision"],\n cache_dir=cache,\n token=False,\n )\n )\n if path.stat().st_size != size:\n raise ValueError("Downloaded asset size differs from pinned metadata")\n with path.open("rb") as stream:\n digest = hashlib.file_digest(stream, "sha256").hexdigest()\n records.append({"filename": filename, "bytes": size, "sha256": digest})\n # Upstream tests often omit revision. Their offline \'"'"'main\'"'"' lookup must\n # resolve to this explicit immutable pin, never the current Hub branch.\n ref = cache / ("models--" + asset["repo_id"].replace("/", "--")) / "refs/main"\n ref.parent.mkdir(parents=True, exist_ok=True)\n ref.write_text(asset["revision"])\n manifests.append({**asset, "files": records, "offline_main": asset["revision"]})\n cache.mkdir(parents=True, exist_ok=True)\n (cache / "tasksmith-assets.json").write_text(json.dumps(manifests, indent=2) + "\\n")\n\nfetch_assets(json.loads(\'"'"'[{"filenames": ["special_tokens_map.json", "tokenizer.json", "tokenizer.model", "tokenizer_config.json"], "max_bytes": 25165824, "repo_id": "hf-internal-testing/dummy-gemma", "revision": "9490194e9c2ab69809ef6b7c231c2836badd3930"}]\'"'"'), Path(\'"'"'/opt/tasksmith-hf/hub\'"'"'))\n'"'"')' +ENV HF_HOME=/opt/tasksmith-hf HF_HUB_CACHE=/opt/tasksmith-hf/hub +COPY source /workspace +RUN python -m pip install --no-cache-dir --no-deps --no-build-isolation -e . +ENV PYTHONDONTWRITEBYTECODE=1 PYTEST_DISABLE_PLUGIN_AUTOLOAD=1 +ENV HF_HUB_OFFLINE=1 TRANSFORMERS_OFFLINE=1 HF_DATASETS_OFFLINE=1 +RUN useradd -m -u 1001 grader +COPY grade.py test_driver.py test_results.py contract.json test.sh /tests/ +RUN chmod 755 /tests && chmod 644 /tests/* diff --git a/tasks/tasksmith-48efdcc71e7d/tests/contract.json b/tasks/tasksmith-48efdcc71e7d/tests/contract.json new file mode 100644 index 0000000000000000000000000000000000000000..de9065b46c9cd0318f78c4f22e535ea196f9fb10 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/contract.json @@ -0,0 +1 @@ +{"expected_passes": ["tests.tasksmith_behavior::test_basic_inference_output_shape", "tests.tasksmith_behavior::test_class_attributes", "tests.tasksmith_behavior::test_encode_prompt_in_isolation", "tests.tasksmith_behavior::test_height_not_divisible_raises", "tests.tasksmith_behavior::test_img2img_importable_from_diffusers", "tests.tasksmith_behavior::test_img2img_importable_from_sana_subpackage", "tests.tasksmith_behavior::test_output_type_latent_returns_tensor", "tests.tasksmith_behavior::test_pregenerated_latents_bypass_vae_encode", "tests.tasksmith_behavior::test_return_dict_false_returns_tuple", "tests.tasksmith_behavior::test_strength_affects_num_timesteps", "tests.tasksmith_behavior::test_strength_out_of_range_raises", "tests.tasksmith_behavior::test_sana_sprint_pipeline_importable", "tests.tasksmith_behavior::test_scm_initial_transformer_input[trimmed]", "tests.tasksmith_behavior::test_scm_initial_transformer_input[full]"], "immutable_assets": {"src/diffusers/experimental/README.md": "c528a2f3a43849ccbde5704392002555e6c24b7161ea4c21c76aa095e3afd16e", "src/diffusers/models/README.md": "c87bf0458e841215dd72c409304c93e02a6cbdbf978fee3868063cd2df3c4114", "src/diffusers/pipelines/README.md": "5c5bcd589f9571ddee23b0f872e6b581371cf4c2968238f3f9b65d56ba7114f1", "src/diffusers/pipelines/deprecated/README.md": "1eec80a862921748539f185bb696101e4bd026fd3b069c99596b7ce378ec3c20", "src/diffusers/pipelines/stable_diffusion/README.md": "09413ef0bf3fc3afa4db28005edd20cc66d9cb456f5958b53ed5d63045bc05b7", "src/diffusers/py.typed": "e3b0c44298fc1c149afbf4c8996fb92427ae41e4649b934ca495991b7852b855", "src/diffusers/schedulers/README.md": "c548789356385c59bfffbec89ad91867e846af659226c7e109f98a1cb2a83c57", "src/diffusers/utils/model_card_template.md": "6611a1ce39cc4f6a0f2db1e70b451844d129542fa8907f8c2ca8ef918b21f83b"}, "optional_files": ["src/diffusers/pipelines/sana/pipeline_sana_sprint_img2img.py"], "submitted_files": ["src/diffusers/__init__.py", "src/diffusers/callbacks.py", "src/diffusers/commands/__init__.py", "src/diffusers/commands/diffusers_cli.py", "src/diffusers/commands/env.py", "src/diffusers/commands/fp16_safetensors.py", "src/diffusers/configuration_utils.py", "src/diffusers/dependency_versions_check.py", "src/diffusers/dependency_versions_table.py", "src/diffusers/experimental/__init__.py", "src/diffusers/experimental/rl/__init__.py", "src/diffusers/experimental/rl/value_guided_sampling.py", "src/diffusers/hooks/__init__.py", "src/diffusers/hooks/faster_cache.py", "src/diffusers/hooks/group_offloading.py", "src/diffusers/hooks/hooks.py", "src/diffusers/hooks/layerwise_casting.py", "src/diffusers/hooks/pyramid_attention_broadcast.py", "src/diffusers/image_processor.py", "src/diffusers/loaders/__init__.py", "src/diffusers/loaders/ip_adapter.py", "src/diffusers/loaders/lora_base.py", "src/diffusers/loaders/lora_conversion_utils.py", "src/diffusers/loaders/lora_pipeline.py", "src/diffusers/loaders/peft.py", "src/diffusers/loaders/single_file.py", "src/diffusers/loaders/single_file_model.py", "src/diffusers/loaders/single_file_utils.py", "src/diffusers/loaders/textual_inversion.py", "src/diffusers/loaders/transformer_flux.py", "src/diffusers/loaders/transformer_sd3.py", "src/diffusers/loaders/unet.py", "src/diffusers/loaders/unet_loader_utils.py", "src/diffusers/loaders/utils.py", "src/diffusers/models/__init__.py", "src/diffusers/models/activations.py", "src/diffusers/models/adapter.py", "src/diffusers/models/attention.py", "src/diffusers/models/attention_flax.py", "src/diffusers/models/attention_processor.py", "src/diffusers/models/auto_model.py", "src/diffusers/models/autoencoders/__init__.py", "src/diffusers/models/autoencoders/autoencoder_asym_kl.py", "src/diffusers/models/autoencoders/autoencoder_dc.py", "src/diffusers/models/autoencoders/autoencoder_kl.py", "src/diffusers/models/autoencoders/autoencoder_kl_allegro.py", "src/diffusers/models/autoencoders/autoencoder_kl_cogvideox.py", "src/diffusers/models/autoencoders/autoencoder_kl_cosmos.py", "src/diffusers/models/autoencoders/autoencoder_kl_hunyuan_video.py", "src/diffusers/models/autoencoders/autoencoder_kl_ltx.py", "src/diffusers/models/autoencoders/autoencoder_kl_magvit.py", "src/diffusers/models/autoencoders/autoencoder_kl_mochi.py", "src/diffusers/models/autoencoders/autoencoder_kl_temporal_decoder.py", "src/diffusers/models/autoencoders/autoencoder_kl_wan.py", "src/diffusers/models/autoencoders/autoencoder_oobleck.py", "src/diffusers/models/autoencoders/autoencoder_tiny.py", "src/diffusers/models/autoencoders/consistency_decoder_vae.py", "src/diffusers/models/autoencoders/vae.py", "src/diffusers/models/autoencoders/vq_model.py", "src/diffusers/models/cache_utils.py", "src/diffusers/models/controlnet.py", "src/diffusers/models/controlnet_flux.py", "src/diffusers/models/controlnet_sd3.py", "src/diffusers/models/controlnet_sparsectrl.py", "src/diffusers/models/controlnets/__init__.py", "src/diffusers/models/controlnets/controlnet.py", "src/diffusers/models/controlnets/controlnet_flax.py", "src/diffusers/models/controlnets/controlnet_flux.py", "src/diffusers/models/controlnets/controlnet_hunyuan.py", "src/diffusers/models/controlnets/controlnet_sana.py", "src/diffusers/models/controlnets/controlnet_sd3.py", "src/diffusers/models/controlnets/controlnet_sparsectrl.py", "src/diffusers/models/controlnets/controlnet_union.py", "src/diffusers/models/controlnets/controlnet_xs.py", "src/diffusers/models/controlnets/multicontrolnet.py", "src/diffusers/models/controlnets/multicontrolnet_union.py", "src/diffusers/models/downsampling.py", "src/diffusers/models/embeddings.py", "src/diffusers/models/embeddings_flax.py", "src/diffusers/models/lora.py", "src/diffusers/models/model_loading_utils.py", "src/diffusers/models/modeling_flax_pytorch_utils.py", "src/diffusers/models/modeling_flax_utils.py", "src/diffusers/models/modeling_outputs.py", "src/diffusers/models/modeling_pytorch_flax_utils.py", "src/diffusers/models/modeling_utils.py", "src/diffusers/models/normalization.py", "src/diffusers/models/resnet.py", "src/diffusers/models/resnet_flax.py", "src/diffusers/models/transformers/__init__.py", "src/diffusers/models/transformers/auraflow_transformer_2d.py", "src/diffusers/models/transformers/cogvideox_transformer_3d.py", "src/diffusers/models/transformers/consisid_transformer_3d.py", "src/diffusers/models/transformers/dit_transformer_2d.py", "src/diffusers/models/transformers/dual_transformer_2d.py", "src/diffusers/models/transformers/hunyuan_transformer_2d.py", "src/diffusers/models/transformers/latte_transformer_3d.py", "src/diffusers/models/transformers/lumina_nextdit2d.py", "src/diffusers/models/transformers/pixart_transformer_2d.py", "src/diffusers/models/transformers/prior_transformer.py", "src/diffusers/models/transformers/sana_transformer.py", "src/diffusers/models/transformers/stable_audio_transformer.py", "src/diffusers/models/transformers/t5_film_transformer.py", "src/diffusers/models/transformers/transformer_2d.py", "src/diffusers/models/transformers/transformer_allegro.py", "src/diffusers/models/transformers/transformer_cogview3plus.py", "src/diffusers/models/transformers/transformer_cogview4.py", "src/diffusers/models/transformers/transformer_cosmos.py", "src/diffusers/models/transformers/transformer_easyanimate.py", "src/diffusers/models/transformers/transformer_flux.py", "src/diffusers/models/transformers/transformer_hidream_image.py", "src/diffusers/models/transformers/transformer_hunyuan_video.py", "src/diffusers/models/transformers/transformer_hunyuan_video_framepack.py", "src/diffusers/models/transformers/transformer_ltx.py", "src/diffusers/models/transformers/transformer_lumina2.py", "src/diffusers/models/transformers/transformer_mochi.py", "src/diffusers/models/transformers/transformer_omnigen.py", "src/diffusers/models/transformers/transformer_sd3.py", "src/diffusers/models/transformers/transformer_temporal.py", "src/diffusers/models/transformers/transformer_wan.py", "src/diffusers/models/unets/__init__.py", "src/diffusers/models/unets/unet_1d.py", "src/diffusers/models/unets/unet_1d_blocks.py", "src/diffusers/models/unets/unet_2d.py", "src/diffusers/models/unets/unet_2d_blocks.py", "src/diffusers/models/unets/unet_2d_blocks_flax.py", "src/diffusers/models/unets/unet_2d_condition.py", "src/diffusers/models/unets/unet_2d_condition_flax.py", "src/diffusers/models/unets/unet_3d_blocks.py", "src/diffusers/models/unets/unet_3d_condition.py", "src/diffusers/models/unets/unet_i2vgen_xl.py", "src/diffusers/models/unets/unet_kandinsky3.py", "src/diffusers/models/unets/unet_motion_model.py", "src/diffusers/models/unets/unet_spatio_temporal_condition.py", "src/diffusers/models/unets/unet_stable_cascade.py", "src/diffusers/models/unets/uvit_2d.py", "src/diffusers/models/upsampling.py", "src/diffusers/models/vae_flax.py", "src/diffusers/models/vq_model.py", "src/diffusers/optimization.py", "src/diffusers/pipelines/__init__.py", "src/diffusers/pipelines/allegro/__init__.py", "src/diffusers/pipelines/allegro/pipeline_allegro.py", "src/diffusers/pipelines/allegro/pipeline_output.py", "src/diffusers/pipelines/amused/__init__.py", "src/diffusers/pipelines/amused/pipeline_amused.py", "src/diffusers/pipelines/amused/pipeline_amused_img2img.py", "src/diffusers/pipelines/amused/pipeline_amused_inpaint.py", "src/diffusers/pipelines/animatediff/__init__.py", "src/diffusers/pipelines/animatediff/pipeline_animatediff.py", "src/diffusers/pipelines/animatediff/pipeline_animatediff_controlnet.py", "src/diffusers/pipelines/animatediff/pipeline_animatediff_sdxl.py", "src/diffusers/pipelines/animatediff/pipeline_animatediff_sparsectrl.py", "src/diffusers/pipelines/animatediff/pipeline_animatediff_video2video.py", "src/diffusers/pipelines/animatediff/pipeline_animatediff_video2video_controlnet.py", "src/diffusers/pipelines/animatediff/pipeline_output.py", "src/diffusers/pipelines/audioldm/__init__.py", "src/diffusers/pipelines/audioldm/pipeline_audioldm.py", "src/diffusers/pipelines/audioldm2/__init__.py", "src/diffusers/pipelines/audioldm2/modeling_audioldm2.py", "src/diffusers/pipelines/audioldm2/pipeline_audioldm2.py", "src/diffusers/pipelines/aura_flow/__init__.py", "src/diffusers/pipelines/aura_flow/pipeline_aura_flow.py", "src/diffusers/pipelines/auto_pipeline.py", "src/diffusers/pipelines/blip_diffusion/__init__.py", "src/diffusers/pipelines/blip_diffusion/blip_image_processing.py", "src/diffusers/pipelines/blip_diffusion/modeling_blip2.py", "src/diffusers/pipelines/blip_diffusion/modeling_ctx_clip.py", "src/diffusers/pipelines/blip_diffusion/pipeline_blip_diffusion.py", "src/diffusers/pipelines/cogvideo/__init__.py", "src/diffusers/pipelines/cogvideo/pipeline_cogvideox.py", "src/diffusers/pipelines/cogvideo/pipeline_cogvideox_fun_control.py", "src/diffusers/pipelines/cogvideo/pipeline_cogvideox_image2video.py", "src/diffusers/pipelines/cogvideo/pipeline_cogvideox_video2video.py", "src/diffusers/pipelines/cogvideo/pipeline_output.py", "src/diffusers/pipelines/cogview3/__init__.py", "src/diffusers/pipelines/cogview3/pipeline_cogview3plus.py", "src/diffusers/pipelines/cogview3/pipeline_output.py", "src/diffusers/pipelines/cogview4/__init__.py", "src/diffusers/pipelines/cogview4/pipeline_cogview4.py", "src/diffusers/pipelines/cogview4/pipeline_cogview4_control.py", "src/diffusers/pipelines/cogview4/pipeline_output.py", "src/diffusers/pipelines/consisid/__init__.py", "src/diffusers/pipelines/consisid/consisid_utils.py", "src/diffusers/pipelines/consisid/pipeline_consisid.py", "src/diffusers/pipelines/consisid/pipeline_output.py", "src/diffusers/pipelines/consistency_models/__init__.py", "src/diffusers/pipelines/consistency_models/pipeline_consistency_models.py", "src/diffusers/pipelines/controlnet/__init__.py", "src/diffusers/pipelines/controlnet/multicontrolnet.py", "src/diffusers/pipelines/controlnet/pipeline_controlnet.py", "src/diffusers/pipelines/controlnet/pipeline_controlnet_blip_diffusion.py", "src/diffusers/pipelines/controlnet/pipeline_controlnet_img2img.py", "src/diffusers/pipelines/controlnet/pipeline_controlnet_inpaint.py", "src/diffusers/pipelines/controlnet/pipeline_controlnet_inpaint_sd_xl.py", "src/diffusers/pipelines/controlnet/pipeline_controlnet_sd_xl.py", "src/diffusers/pipelines/controlnet/pipeline_controlnet_sd_xl_img2img.py", "src/diffusers/pipelines/controlnet/pipeline_controlnet_union_inpaint_sd_xl.py", "src/diffusers/pipelines/controlnet/pipeline_controlnet_union_sd_xl.py", "src/diffusers/pipelines/controlnet/pipeline_controlnet_union_sd_xl_img2img.py", "src/diffusers/pipelines/controlnet/pipeline_flax_controlnet.py", "src/diffusers/pipelines/controlnet_hunyuandit/__init__.py", "src/diffusers/pipelines/controlnet_hunyuandit/pipeline_hunyuandit_controlnet.py", "src/diffusers/pipelines/controlnet_sd3/__init__.py", "src/diffusers/pipelines/controlnet_sd3/pipeline_stable_diffusion_3_controlnet.py", "src/diffusers/pipelines/controlnet_sd3/pipeline_stable_diffusion_3_controlnet_inpainting.py", "src/diffusers/pipelines/controlnet_xs/__init__.py", "src/diffusers/pipelines/controlnet_xs/pipeline_controlnet_xs.py", "src/diffusers/pipelines/controlnet_xs/pipeline_controlnet_xs_sd_xl.py", "src/diffusers/pipelines/cosmos/__init__.py", "src/diffusers/pipelines/cosmos/pipeline_cosmos_text2world.py", "src/diffusers/pipelines/cosmos/pipeline_cosmos_video2world.py", "src/diffusers/pipelines/cosmos/pipeline_output.py", "src/diffusers/pipelines/dance_diffusion/__init__.py", "src/diffusers/pipelines/dance_diffusion/pipeline_dance_diffusion.py", "src/diffusers/pipelines/ddim/__init__.py", "src/diffusers/pipelines/ddim/pipeline_ddim.py", "src/diffusers/pipelines/ddpm/__init__.py", "src/diffusers/pipelines/ddpm/pipeline_ddpm.py", "src/diffusers/pipelines/deepfloyd_if/__init__.py", "src/diffusers/pipelines/deepfloyd_if/pipeline_if.py", "src/diffusers/pipelines/deepfloyd_if/pipeline_if_img2img.py", "src/diffusers/pipelines/deepfloyd_if/pipeline_if_img2img_superresolution.py", "src/diffusers/pipelines/deepfloyd_if/pipeline_if_inpainting.py", "src/diffusers/pipelines/deepfloyd_if/pipeline_if_inpainting_superresolution.py", "src/diffusers/pipelines/deepfloyd_if/pipeline_if_superresolution.py", "src/diffusers/pipelines/deepfloyd_if/pipeline_output.py", "src/diffusers/pipelines/deepfloyd_if/safety_checker.py", "src/diffusers/pipelines/deepfloyd_if/timesteps.py", "src/diffusers/pipelines/deepfloyd_if/watermark.py", "src/diffusers/pipelines/deprecated/__init__.py", "src/diffusers/pipelines/deprecated/alt_diffusion/__init__.py", "src/diffusers/pipelines/deprecated/alt_diffusion/modeling_roberta_series.py", "src/diffusers/pipelines/deprecated/alt_diffusion/pipeline_alt_diffusion.py", "src/diffusers/pipelines/deprecated/alt_diffusion/pipeline_alt_diffusion_img2img.py", "src/diffusers/pipelines/deprecated/alt_diffusion/pipeline_output.py", "src/diffusers/pipelines/deprecated/audio_diffusion/__init__.py", "src/diffusers/pipelines/deprecated/audio_diffusion/mel.py", "src/diffusers/pipelines/deprecated/audio_diffusion/pipeline_audio_diffusion.py", "src/diffusers/pipelines/deprecated/latent_diffusion_uncond/__init__.py", "src/diffusers/pipelines/deprecated/latent_diffusion_uncond/pipeline_latent_diffusion_uncond.py", "src/diffusers/pipelines/deprecated/pndm/__init__.py", "src/diffusers/pipelines/deprecated/pndm/pipeline_pndm.py", "src/diffusers/pipelines/deprecated/repaint/__init__.py", "src/diffusers/pipelines/deprecated/repaint/pipeline_repaint.py", "src/diffusers/pipelines/deprecated/score_sde_ve/__init__.py", "src/diffusers/pipelines/deprecated/score_sde_ve/pipeline_score_sde_ve.py", "src/diffusers/pipelines/deprecated/spectrogram_diffusion/__init__.py", "src/diffusers/pipelines/deprecated/spectrogram_diffusion/continuous_encoder.py", "src/diffusers/pipelines/deprecated/spectrogram_diffusion/midi_utils.py", "src/diffusers/pipelines/deprecated/spectrogram_diffusion/notes_encoder.py", "src/diffusers/pipelines/deprecated/spectrogram_diffusion/pipeline_spectrogram_diffusion.py", "src/diffusers/pipelines/deprecated/stable_diffusion_variants/__init__.py", "src/diffusers/pipelines/deprecated/stable_diffusion_variants/pipeline_cycle_diffusion.py", "src/diffusers/pipelines/deprecated/stable_diffusion_variants/pipeline_onnx_stable_diffusion_inpaint_legacy.py", "src/diffusers/pipelines/deprecated/stable_diffusion_variants/pipeline_stable_diffusion_inpaint_legacy.py", "src/diffusers/pipelines/deprecated/stable_diffusion_variants/pipeline_stable_diffusion_model_editing.py", "src/diffusers/pipelines/deprecated/stable_diffusion_variants/pipeline_stable_diffusion_paradigms.py", "src/diffusers/pipelines/deprecated/stable_diffusion_variants/pipeline_stable_diffusion_pix2pix_zero.py", "src/diffusers/pipelines/deprecated/stochastic_karras_ve/__init__.py", "src/diffusers/pipelines/deprecated/stochastic_karras_ve/pipeline_stochastic_karras_ve.py", "src/diffusers/pipelines/deprecated/versatile_diffusion/__init__.py", "src/diffusers/pipelines/deprecated/versatile_diffusion/modeling_text_unet.py", "src/diffusers/pipelines/deprecated/versatile_diffusion/pipeline_versatile_diffusion.py", "src/diffusers/pipelines/deprecated/versatile_diffusion/pipeline_versatile_diffusion_dual_guided.py", "src/diffusers/pipelines/deprecated/versatile_diffusion/pipeline_versatile_diffusion_image_variation.py", "src/diffusers/pipelines/deprecated/versatile_diffusion/pipeline_versatile_diffusion_text_to_image.py", "src/diffusers/pipelines/deprecated/vq_diffusion/__init__.py", "src/diffusers/pipelines/deprecated/vq_diffusion/pipeline_vq_diffusion.py", "src/diffusers/pipelines/dit/__init__.py", "src/diffusers/pipelines/dit/pipeline_dit.py", "src/diffusers/pipelines/easyanimate/__init__.py", "src/diffusers/pipelines/easyanimate/pipeline_easyanimate.py", "src/diffusers/pipelines/easyanimate/pipeline_easyanimate_control.py", "src/diffusers/pipelines/easyanimate/pipeline_easyanimate_inpaint.py", "src/diffusers/pipelines/easyanimate/pipeline_output.py", "src/diffusers/pipelines/flux/__init__.py", "src/diffusers/pipelines/flux/modeling_flux.py", "src/diffusers/pipelines/flux/pipeline_flux.py", "src/diffusers/pipelines/flux/pipeline_flux_control.py", "src/diffusers/pipelines/flux/pipeline_flux_control_img2img.py", "src/diffusers/pipelines/flux/pipeline_flux_control_inpaint.py", "src/diffusers/pipelines/flux/pipeline_flux_controlnet.py", "src/diffusers/pipelines/flux/pipeline_flux_controlnet_image_to_image.py", "src/diffusers/pipelines/flux/pipeline_flux_controlnet_inpainting.py", "src/diffusers/pipelines/flux/pipeline_flux_fill.py", "src/diffusers/pipelines/flux/pipeline_flux_img2img.py", "src/diffusers/pipelines/flux/pipeline_flux_inpaint.py", "src/diffusers/pipelines/flux/pipeline_flux_prior_redux.py", "src/diffusers/pipelines/flux/pipeline_output.py", "src/diffusers/pipelines/free_init_utils.py", "src/diffusers/pipelines/free_noise_utils.py", "src/diffusers/pipelines/hidream_image/__init__.py", "src/diffusers/pipelines/hidream_image/pipeline_hidream_image.py", "src/diffusers/pipelines/hidream_image/pipeline_output.py", "src/diffusers/pipelines/hunyuan_video/__init__.py", "src/diffusers/pipelines/hunyuan_video/pipeline_hunyuan_skyreels_image2video.py", "src/diffusers/pipelines/hunyuan_video/pipeline_hunyuan_video.py", "src/diffusers/pipelines/hunyuan_video/pipeline_hunyuan_video_framepack.py", "src/diffusers/pipelines/hunyuan_video/pipeline_hunyuan_video_image2video.py", "src/diffusers/pipelines/hunyuan_video/pipeline_output.py", "src/diffusers/pipelines/hunyuandit/__init__.py", "src/diffusers/pipelines/hunyuandit/pipeline_hunyuandit.py", "src/diffusers/pipelines/i2vgen_xl/__init__.py", "src/diffusers/pipelines/i2vgen_xl/pipeline_i2vgen_xl.py", "src/diffusers/pipelines/kandinsky/__init__.py", "src/diffusers/pipelines/kandinsky/pipeline_kandinsky.py", "src/diffusers/pipelines/kandinsky/pipeline_kandinsky_combined.py", "src/diffusers/pipelines/kandinsky/pipeline_kandinsky_img2img.py", "src/diffusers/pipelines/kandinsky/pipeline_kandinsky_inpaint.py", "src/diffusers/pipelines/kandinsky/pipeline_kandinsky_prior.py", "src/diffusers/pipelines/kandinsky/text_encoder.py", "src/diffusers/pipelines/kandinsky2_2/__init__.py", "src/diffusers/pipelines/kandinsky2_2/pipeline_kandinsky2_2.py", "src/diffusers/pipelines/kandinsky2_2/pipeline_kandinsky2_2_combined.py", "src/diffusers/pipelines/kandinsky2_2/pipeline_kandinsky2_2_controlnet.py", "src/diffusers/pipelines/kandinsky2_2/pipeline_kandinsky2_2_controlnet_img2img.py", "src/diffusers/pipelines/kandinsky2_2/pipeline_kandinsky2_2_img2img.py", "src/diffusers/pipelines/kandinsky2_2/pipeline_kandinsky2_2_inpainting.py", "src/diffusers/pipelines/kandinsky2_2/pipeline_kandinsky2_2_prior.py", "src/diffusers/pipelines/kandinsky2_2/pipeline_kandinsky2_2_prior_emb2emb.py", "src/diffusers/pipelines/kandinsky3/__init__.py", "src/diffusers/pipelines/kandinsky3/convert_kandinsky3_unet.py", "src/diffusers/pipelines/kandinsky3/pipeline_kandinsky3.py", "src/diffusers/pipelines/kandinsky3/pipeline_kandinsky3_img2img.py", "src/diffusers/pipelines/kolors/__init__.py", "src/diffusers/pipelines/kolors/pipeline_kolors.py", "src/diffusers/pipelines/kolors/pipeline_kolors_img2img.py", "src/diffusers/pipelines/kolors/pipeline_output.py", "src/diffusers/pipelines/kolors/text_encoder.py", "src/diffusers/pipelines/kolors/tokenizer.py", "src/diffusers/pipelines/latent_consistency_models/__init__.py", "src/diffusers/pipelines/latent_consistency_models/pipeline_latent_consistency_img2img.py", "src/diffusers/pipelines/latent_consistency_models/pipeline_latent_consistency_text2img.py", "src/diffusers/pipelines/latent_diffusion/__init__.py", "src/diffusers/pipelines/latent_diffusion/pipeline_latent_diffusion.py", "src/diffusers/pipelines/latent_diffusion/pipeline_latent_diffusion_superresolution.py", "src/diffusers/pipelines/latte/__init__.py", "src/diffusers/pipelines/latte/pipeline_latte.py", "src/diffusers/pipelines/ledits_pp/__init__.py", "src/diffusers/pipelines/ledits_pp/pipeline_leditspp_stable_diffusion.py", "src/diffusers/pipelines/ledits_pp/pipeline_leditspp_stable_diffusion_xl.py", "src/diffusers/pipelines/ledits_pp/pipeline_output.py", "src/diffusers/pipelines/ltx/__init__.py", "src/diffusers/pipelines/ltx/modeling_latent_upsampler.py", "src/diffusers/pipelines/ltx/pipeline_ltx.py", "src/diffusers/pipelines/ltx/pipeline_ltx_condition.py", "src/diffusers/pipelines/ltx/pipeline_ltx_image2video.py", "src/diffusers/pipelines/ltx/pipeline_ltx_latent_upsample.py", "src/diffusers/pipelines/ltx/pipeline_output.py", "src/diffusers/pipelines/lumina/__init__.py", "src/diffusers/pipelines/lumina/pipeline_lumina.py", "src/diffusers/pipelines/lumina2/__init__.py", "src/diffusers/pipelines/lumina2/pipeline_lumina2.py", "src/diffusers/pipelines/marigold/__init__.py", "src/diffusers/pipelines/marigold/marigold_image_processing.py", "src/diffusers/pipelines/marigold/pipeline_marigold_depth.py", "src/diffusers/pipelines/marigold/pipeline_marigold_intrinsics.py", "src/diffusers/pipelines/marigold/pipeline_marigold_normals.py", "src/diffusers/pipelines/mochi/__init__.py", "src/diffusers/pipelines/mochi/pipeline_mochi.py", "src/diffusers/pipelines/mochi/pipeline_output.py", "src/diffusers/pipelines/musicldm/__init__.py", "src/diffusers/pipelines/musicldm/pipeline_musicldm.py", "src/diffusers/pipelines/omnigen/__init__.py", "src/diffusers/pipelines/omnigen/pipeline_omnigen.py", "src/diffusers/pipelines/omnigen/processor_omnigen.py", "src/diffusers/pipelines/onnx_utils.py", "src/diffusers/pipelines/pag/__init__.py", "src/diffusers/pipelines/pag/pag_utils.py", "src/diffusers/pipelines/pag/pipeline_pag_controlnet_sd.py", "src/diffusers/pipelines/pag/pipeline_pag_controlnet_sd_inpaint.py", "src/diffusers/pipelines/pag/pipeline_pag_controlnet_sd_xl.py", "src/diffusers/pipelines/pag/pipeline_pag_controlnet_sd_xl_img2img.py", "src/diffusers/pipelines/pag/pipeline_pag_hunyuandit.py", "src/diffusers/pipelines/pag/pipeline_pag_kolors.py", "src/diffusers/pipelines/pag/pipeline_pag_pixart_sigma.py", "src/diffusers/pipelines/pag/pipeline_pag_sana.py", "src/diffusers/pipelines/pag/pipeline_pag_sd.py", "src/diffusers/pipelines/pag/pipeline_pag_sd_3.py", "src/diffusers/pipelines/pag/pipeline_pag_sd_3_img2img.py", "src/diffusers/pipelines/pag/pipeline_pag_sd_animatediff.py", "src/diffusers/pipelines/pag/pipeline_pag_sd_img2img.py", "src/diffusers/pipelines/pag/pipeline_pag_sd_inpaint.py", "src/diffusers/pipelines/pag/pipeline_pag_sd_xl.py", "src/diffusers/pipelines/pag/pipeline_pag_sd_xl_img2img.py", "src/diffusers/pipelines/pag/pipeline_pag_sd_xl_inpaint.py", "src/diffusers/pipelines/paint_by_example/__init__.py", "src/diffusers/pipelines/paint_by_example/image_encoder.py", "src/diffusers/pipelines/paint_by_example/pipeline_paint_by_example.py", "src/diffusers/pipelines/pia/__init__.py", "src/diffusers/pipelines/pia/pipeline_pia.py", "src/diffusers/pipelines/pipeline_flax_utils.py", "src/diffusers/pipelines/pipeline_loading_utils.py", "src/diffusers/pipelines/pipeline_utils.py", "src/diffusers/pipelines/pixart_alpha/__init__.py", "src/diffusers/pipelines/pixart_alpha/pipeline_pixart_alpha.py", "src/diffusers/pipelines/pixart_alpha/pipeline_pixart_sigma.py", "src/diffusers/pipelines/sana/__init__.py", "src/diffusers/pipelines/sana/pipeline_output.py", "src/diffusers/pipelines/sana/pipeline_sana.py", "src/diffusers/pipelines/sana/pipeline_sana_controlnet.py", "src/diffusers/pipelines/sana/pipeline_sana_sprint.py", "src/diffusers/pipelines/sana/pipeline_sana_sprint_img2img.py", "src/diffusers/pipelines/semantic_stable_diffusion/__init__.py", "src/diffusers/pipelines/semantic_stable_diffusion/pipeline_output.py", "src/diffusers/pipelines/semantic_stable_diffusion/pipeline_semantic_stable_diffusion.py", "src/diffusers/pipelines/shap_e/__init__.py", "src/diffusers/pipelines/shap_e/camera.py", "src/diffusers/pipelines/shap_e/pipeline_shap_e.py", "src/diffusers/pipelines/shap_e/pipeline_shap_e_img2img.py", "src/diffusers/pipelines/shap_e/renderer.py", "src/diffusers/pipelines/stable_audio/__init__.py", "src/diffusers/pipelines/stable_audio/modeling_stable_audio.py", "src/diffusers/pipelines/stable_audio/pipeline_stable_audio.py", "src/diffusers/pipelines/stable_cascade/__init__.py", "src/diffusers/pipelines/stable_cascade/pipeline_stable_cascade.py", "src/diffusers/pipelines/stable_cascade/pipeline_stable_cascade_combined.py", "src/diffusers/pipelines/stable_cascade/pipeline_stable_cascade_prior.py", "src/diffusers/pipelines/stable_diffusion/__init__.py", "src/diffusers/pipelines/stable_diffusion/clip_image_project_model.py", "src/diffusers/pipelines/stable_diffusion/convert_from_ckpt.py", "src/diffusers/pipelines/stable_diffusion/pipeline_flax_stable_diffusion.py", "src/diffusers/pipelines/stable_diffusion/pipeline_flax_stable_diffusion_img2img.py", "src/diffusers/pipelines/stable_diffusion/pipeline_flax_stable_diffusion_inpaint.py", "src/diffusers/pipelines/stable_diffusion/pipeline_onnx_stable_diffusion.py", "src/diffusers/pipelines/stable_diffusion/pipeline_onnx_stable_diffusion_img2img.py", "src/diffusers/pipelines/stable_diffusion/pipeline_onnx_stable_diffusion_inpaint.py", "src/diffusers/pipelines/stable_diffusion/pipeline_onnx_stable_diffusion_upscale.py", "src/diffusers/pipelines/stable_diffusion/pipeline_output.py", "src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion.py", "src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_depth2img.py", "src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_image_variation.py", "src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_img2img.py", "src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_inpaint.py", "src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_instruct_pix2pix.py", "src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_latent_upscale.py", "src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_upscale.py", "src/diffusers/pipelines/stable_diffusion/pipeline_stable_unclip.py", "src/diffusers/pipelines/stable_diffusion/pipeline_stable_unclip_img2img.py", "src/diffusers/pipelines/stable_diffusion/safety_checker.py", "src/diffusers/pipelines/stable_diffusion/safety_checker_flax.py", "src/diffusers/pipelines/stable_diffusion/stable_unclip_image_normalizer.py", "src/diffusers/pipelines/stable_diffusion_3/__init__.py", "src/diffusers/pipelines/stable_diffusion_3/pipeline_output.py", "src/diffusers/pipelines/stable_diffusion_3/pipeline_stable_diffusion_3.py", "src/diffusers/pipelines/stable_diffusion_3/pipeline_stable_diffusion_3_img2img.py", "src/diffusers/pipelines/stable_diffusion_3/pipeline_stable_diffusion_3_inpaint.py", "src/diffusers/pipelines/stable_diffusion_attend_and_excite/__init__.py", "src/diffusers/pipelines/stable_diffusion_attend_and_excite/pipeline_stable_diffusion_attend_and_excite.py", "src/diffusers/pipelines/stable_diffusion_diffedit/__init__.py", "src/diffusers/pipelines/stable_diffusion_diffedit/pipeline_stable_diffusion_diffedit.py", "src/diffusers/pipelines/stable_diffusion_gligen/__init__.py", "src/diffusers/pipelines/stable_diffusion_gligen/pipeline_stable_diffusion_gligen.py", "src/diffusers/pipelines/stable_diffusion_gligen/pipeline_stable_diffusion_gligen_text_image.py", "src/diffusers/pipelines/stable_diffusion_k_diffusion/__init__.py", "src/diffusers/pipelines/stable_diffusion_k_diffusion/pipeline_stable_diffusion_k_diffusion.py", "src/diffusers/pipelines/stable_diffusion_k_diffusion/pipeline_stable_diffusion_xl_k_diffusion.py", "src/diffusers/pipelines/stable_diffusion_ldm3d/__init__.py", "src/diffusers/pipelines/stable_diffusion_ldm3d/pipeline_stable_diffusion_ldm3d.py", "src/diffusers/pipelines/stable_diffusion_panorama/__init__.py", "src/diffusers/pipelines/stable_diffusion_panorama/pipeline_stable_diffusion_panorama.py", "src/diffusers/pipelines/stable_diffusion_safe/__init__.py", "src/diffusers/pipelines/stable_diffusion_safe/pipeline_output.py", "src/diffusers/pipelines/stable_diffusion_safe/pipeline_stable_diffusion_safe.py", "src/diffusers/pipelines/stable_diffusion_safe/safety_checker.py", "src/diffusers/pipelines/stable_diffusion_sag/__init__.py", "src/diffusers/pipelines/stable_diffusion_sag/pipeline_stable_diffusion_sag.py", "src/diffusers/pipelines/stable_diffusion_xl/__init__.py", "src/diffusers/pipelines/stable_diffusion_xl/pipeline_flax_stable_diffusion_xl.py", "src/diffusers/pipelines/stable_diffusion_xl/pipeline_output.py", "src/diffusers/pipelines/stable_diffusion_xl/pipeline_stable_diffusion_xl.py", "src/diffusers/pipelines/stable_diffusion_xl/pipeline_stable_diffusion_xl_img2img.py", "src/diffusers/pipelines/stable_diffusion_xl/pipeline_stable_diffusion_xl_inpaint.py", "src/diffusers/pipelines/stable_diffusion_xl/pipeline_stable_diffusion_xl_instruct_pix2pix.py", "src/diffusers/pipelines/stable_diffusion_xl/watermark.py", "src/diffusers/pipelines/stable_video_diffusion/__init__.py", "src/diffusers/pipelines/stable_video_diffusion/pipeline_stable_video_diffusion.py", "src/diffusers/pipelines/t2i_adapter/__init__.py", "src/diffusers/pipelines/t2i_adapter/pipeline_stable_diffusion_adapter.py", "src/diffusers/pipelines/t2i_adapter/pipeline_stable_diffusion_xl_adapter.py", "src/diffusers/pipelines/text_to_video_synthesis/__init__.py", "src/diffusers/pipelines/text_to_video_synthesis/pipeline_output.py", "src/diffusers/pipelines/text_to_video_synthesis/pipeline_text_to_video_synth.py", "src/diffusers/pipelines/text_to_video_synthesis/pipeline_text_to_video_synth_img2img.py", "src/diffusers/pipelines/text_to_video_synthesis/pipeline_text_to_video_zero.py", "src/diffusers/pipelines/text_to_video_synthesis/pipeline_text_to_video_zero_sdxl.py", "src/diffusers/pipelines/transformers_loading_utils.py", "src/diffusers/pipelines/unclip/__init__.py", "src/diffusers/pipelines/unclip/pipeline_unclip.py", "src/diffusers/pipelines/unclip/pipeline_unclip_image_variation.py", "src/diffusers/pipelines/unclip/text_proj.py", "src/diffusers/pipelines/unidiffuser/__init__.py", "src/diffusers/pipelines/unidiffuser/modeling_text_decoder.py", "src/diffusers/pipelines/unidiffuser/modeling_uvit.py", "src/diffusers/pipelines/unidiffuser/pipeline_unidiffuser.py", "src/diffusers/pipelines/visualcloze/__init__.py", "src/diffusers/pipelines/visualcloze/pipeline_visualcloze_combined.py", "src/diffusers/pipelines/visualcloze/pipeline_visualcloze_generation.py", "src/diffusers/pipelines/visualcloze/visualcloze_utils.py", "src/diffusers/pipelines/wan/__init__.py", "src/diffusers/pipelines/wan/pipeline_output.py", "src/diffusers/pipelines/wan/pipeline_wan.py", "src/diffusers/pipelines/wan/pipeline_wan_i2v.py", "src/diffusers/pipelines/wan/pipeline_wan_video2video.py", "src/diffusers/pipelines/wuerstchen/__init__.py", "src/diffusers/pipelines/wuerstchen/modeling_paella_vq_model.py", "src/diffusers/pipelines/wuerstchen/modeling_wuerstchen_common.py", "src/diffusers/pipelines/wuerstchen/modeling_wuerstchen_diffnext.py", "src/diffusers/pipelines/wuerstchen/modeling_wuerstchen_prior.py", "src/diffusers/pipelines/wuerstchen/pipeline_wuerstchen.py", "src/diffusers/pipelines/wuerstchen/pipeline_wuerstchen_combined.py", "src/diffusers/pipelines/wuerstchen/pipeline_wuerstchen_prior.py", "src/diffusers/quantizers/__init__.py", "src/diffusers/quantizers/auto.py", "src/diffusers/quantizers/base.py", "src/diffusers/quantizers/bitsandbytes/__init__.py", "src/diffusers/quantizers/bitsandbytes/bnb_quantizer.py", "src/diffusers/quantizers/bitsandbytes/utils.py", "src/diffusers/quantizers/gguf/__init__.py", "src/diffusers/quantizers/gguf/gguf_quantizer.py", "src/diffusers/quantizers/gguf/utils.py", "src/diffusers/quantizers/quantization_config.py", "src/diffusers/quantizers/quanto/__init__.py", "src/diffusers/quantizers/quanto/quanto_quantizer.py", "src/diffusers/quantizers/quanto/utils.py", "src/diffusers/quantizers/torchao/__init__.py", "src/diffusers/quantizers/torchao/torchao_quantizer.py", "src/diffusers/schedulers/__init__.py", "src/diffusers/schedulers/deprecated/__init__.py", "src/diffusers/schedulers/deprecated/scheduling_karras_ve.py", "src/diffusers/schedulers/deprecated/scheduling_sde_vp.py", "src/diffusers/schedulers/scheduling_amused.py", "src/diffusers/schedulers/scheduling_consistency_decoder.py", "src/diffusers/schedulers/scheduling_consistency_models.py", "src/diffusers/schedulers/scheduling_cosine_dpmsolver_multistep.py", "src/diffusers/schedulers/scheduling_ddim.py", "src/diffusers/schedulers/scheduling_ddim_cogvideox.py", "src/diffusers/schedulers/scheduling_ddim_flax.py", "src/diffusers/schedulers/scheduling_ddim_inverse.py", "src/diffusers/schedulers/scheduling_ddim_parallel.py", "src/diffusers/schedulers/scheduling_ddpm.py", "src/diffusers/schedulers/scheduling_ddpm_flax.py", "src/diffusers/schedulers/scheduling_ddpm_parallel.py", "src/diffusers/schedulers/scheduling_ddpm_wuerstchen.py", "src/diffusers/schedulers/scheduling_deis_multistep.py", "src/diffusers/schedulers/scheduling_dpm_cogvideox.py", "src/diffusers/schedulers/scheduling_dpmsolver_multistep.py", "src/diffusers/schedulers/scheduling_dpmsolver_multistep_flax.py", "src/diffusers/schedulers/scheduling_dpmsolver_multistep_inverse.py", "src/diffusers/schedulers/scheduling_dpmsolver_sde.py", "src/diffusers/schedulers/scheduling_dpmsolver_singlestep.py", "src/diffusers/schedulers/scheduling_edm_dpmsolver_multistep.py", "src/diffusers/schedulers/scheduling_edm_euler.py", "src/diffusers/schedulers/scheduling_euler_ancestral_discrete.py", "src/diffusers/schedulers/scheduling_euler_discrete.py", "src/diffusers/schedulers/scheduling_euler_discrete_flax.py", "src/diffusers/schedulers/scheduling_flow_match_euler_discrete.py", "src/diffusers/schedulers/scheduling_flow_match_heun_discrete.py", "src/diffusers/schedulers/scheduling_flow_match_lcm.py", "src/diffusers/schedulers/scheduling_heun_discrete.py", "src/diffusers/schedulers/scheduling_ipndm.py", "src/diffusers/schedulers/scheduling_k_dpm_2_ancestral_discrete.py", "src/diffusers/schedulers/scheduling_k_dpm_2_discrete.py", "src/diffusers/schedulers/scheduling_karras_ve_flax.py", "src/diffusers/schedulers/scheduling_lcm.py", "src/diffusers/schedulers/scheduling_lms_discrete.py", "src/diffusers/schedulers/scheduling_lms_discrete_flax.py", "src/diffusers/schedulers/scheduling_pndm.py", "src/diffusers/schedulers/scheduling_pndm_flax.py", "src/diffusers/schedulers/scheduling_repaint.py", "src/diffusers/schedulers/scheduling_sasolver.py", "src/diffusers/schedulers/scheduling_scm.py", "src/diffusers/schedulers/scheduling_sde_ve.py", "src/diffusers/schedulers/scheduling_sde_ve_flax.py", "src/diffusers/schedulers/scheduling_tcd.py", "src/diffusers/schedulers/scheduling_unclip.py", "src/diffusers/schedulers/scheduling_unipc_multistep.py", "src/diffusers/schedulers/scheduling_utils.py", "src/diffusers/schedulers/scheduling_utils_flax.py", "src/diffusers/schedulers/scheduling_vq_diffusion.py", "src/diffusers/training_utils.py", "src/diffusers/utils/__init__.py", "src/diffusers/utils/accelerate_utils.py", "src/diffusers/utils/constants.py", "src/diffusers/utils/deprecation_utils.py", "src/diffusers/utils/doc_utils.py", "src/diffusers/utils/dummy_bitsandbytes_objects.py", "src/diffusers/utils/dummy_flax_and_transformers_objects.py", "src/diffusers/utils/dummy_flax_objects.py", "src/diffusers/utils/dummy_gguf_objects.py", "src/diffusers/utils/dummy_note_seq_objects.py", "src/diffusers/utils/dummy_onnx_objects.py", "src/diffusers/utils/dummy_optimum_quanto_objects.py", "src/diffusers/utils/dummy_pt_objects.py", "src/diffusers/utils/dummy_torch_and_librosa_objects.py", "src/diffusers/utils/dummy_torch_and_scipy_objects.py", "src/diffusers/utils/dummy_torch_and_torchsde_objects.py", "src/diffusers/utils/dummy_torch_and_transformers_and_k_diffusion_objects.py", "src/diffusers/utils/dummy_torch_and_transformers_and_onnx_objects.py", "src/diffusers/utils/dummy_torch_and_transformers_and_opencv_objects.py", "src/diffusers/utils/dummy_torch_and_transformers_and_sentencepiece_objects.py", "src/diffusers/utils/dummy_torch_and_transformers_objects.py", "src/diffusers/utils/dummy_torchao_objects.py", "src/diffusers/utils/dummy_transformers_and_torch_and_note_seq_objects.py", "src/diffusers/utils/dynamic_modules_utils.py", "src/diffusers/utils/export_utils.py", "src/diffusers/utils/hub_utils.py", "src/diffusers/utils/import_utils.py", "src/diffusers/utils/loading_utils.py", "src/diffusers/utils/logging.py", "src/diffusers/utils/outputs.py", "src/diffusers/utils/peft_utils.py", "src/diffusers/utils/pil_utils.py", "src/diffusers/utils/remote_utils.py", "src/diffusers/utils/source_code_parsing_utils.py", "src/diffusers/utils/state_dict_utils.py", "src/diffusers/utils/testing_utils.py", "src/diffusers/utils/torch_utils.py", "src/diffusers/utils/typing_utils.py", "src/diffusers/utils/versions.py", "src/diffusers/video_processor.py"], "submitted_roots": ["src/diffusers"], "test_paths": ["tests/tasksmith_behavior.py"], "timeout_sec": 240} \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/grade.py b/tasks/tasksmith-48efdcc71e7d/tests/grade.py new file mode 100644 index 0000000000000000000000000000000000000000..7e060dd2eaf372c0e83ae8f5aea784e5bd622402 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/grade.py @@ -0,0 +1,188 @@ +"""Standalone trusted entry point; copied into each separate verifier image. + +No Repo2RLEnv installation is needed to grade an exported task. Submitted Python +runs as an unprivileged user; this parent owns the result parser and reward file. +""" + +from __future__ import annotations + +import hashlib +import importlib.util +import json +import os +import signal +import stat +import subprocess +import sys +import tempfile +from pathlib import Path + + +def child_environment(temporary: str) -> dict[str, str]: + """Preserve prepared runtime assets without inheriting controller credentials.""" + return { + **{ + key: os.environ[key] + for key in ( + "LD_LIBRARY_PATH", + "CUDA_VISIBLE_DEVICES", + "NVIDIA_VISIBLE_DEVICES", + "NVIDIA_DRIVER_CAPABILITIES", + "NCCL_SOCKET_IFNAME", + "GLOO_SOCKET_IFNAME", + "HF_HOME", + "HF_HUB_CACHE", + "HF_HUB_OFFLINE", + "TRANSFORMERS_OFFLINE", + "HF_DATASETS_OFFLINE", + ) + if key in os.environ + }, + "PATH": str(Path(sys.executable).parent) + ":/usr/local/bin:/usr/bin:/bin", + "HOME": temporary, + "PYTHONDONTWRITEBYTECODE": "1", + "PYTEST_DISABLE_PLUGIN_AUTOLOAD": "1", + } + + +def validate_submission(workspace: Path, contract: dict) -> None: + """Validate private staging and remove inert backups before importing Python.""" + submitted = set(contract["submitted_files"]) + backups: set[str] = set() + optional = submitted & set(contract.get("optional_files", [])) + paths = submitted - optional + for relative in optional: + path = workspace / relative + if any(component.is_symlink() for component in (path, *path.parents)): + raise ValueError("Submitted source contains a symlink") + # Added standalone modules may be absent in the baseline. If supplied, + # apply the same regular-file and size checks as every required module. + if path.exists(): + paths.add(relative) + roots = contract.get("submitted_roots", []) + immutable = contract.get("immutable_assets", {}) + paths.update(immutable) + for relative in roots: + root = workspace / relative + if root.is_symlink() or not root.is_dir(): + raise ValueError("Submitted source root is missing or linked") + for path in root.rglob("*"): + if path.is_symlink(): + raise ValueError("Submitted source contains a symlink") + if path.is_dir(): + continue + name = path.relative_to(workspace).as_posix() + if path.suffix != ".py" and name not in immutable: + if name not in submitted and path.name.endswith((".py.bak", ".py~")): + backups.add(name) + else: + raise ValueError("Only Python source files may be added") + paths.add(name) + for relative in sorted(paths): + path = workspace / relative + for component in (path, *path.parents): + if component.is_symlink(): + raise ValueError("Submitted source contains a symlink") + if ( + not path.is_file() + or not stat.S_ISREG(path.stat().st_mode) + or path.stat().st_size > 8 * 1024 * 1024 + ): + raise ValueError("Submitted source is not a bounded regular file") + if ( + relative in immutable + and hashlib.sha256(path.read_bytes()).hexdigest() != immutable[relative] + ): + raise ValueError("Non-Python source assets must remain unchanged") + if relative not in backups: + os.chown(path, 0, 0) + path.chmod(0o644) + # Only the verifier's collected copy is cleaned. The learner workspace and + # archived submission retain their bytes. Validate every path first so a + # backup cannot bypass linked, oversized, required, or immutable file checks. + for relative in sorted(backups): + (workspace / relative).unlink() + + +def main() -> None: + directory = Path("/tests") + parser_spec = importlib.util.spec_from_file_location( + "test_results", directory / "test_results.py" + ) + parser = importlib.util.module_from_spec(parser_spec) + sys.modules[parser_spec.name] = parser + parser_spec.loader.exec_module(parser) + contract = json.loads((directory / "contract.json").read_text()) + logs = Path("/logs/verifier") + logs.mkdir(parents=True, exist_ok=True) + logs.chmod(0o755) + reward = logs / "reward.txt" + reward.write_text("0\n") + reward.chmod(0o644) + try: + validate_submission(Path("/workspace"), contract) + except (ValueError, OSError) as exc: + (logs / "result.json").write_text(json.dumps({"passed": False, "reason": str(exc)})) + return + with tempfile.TemporaryDirectory(prefix="r2e-grade-") as temporary: + working = Path(temporary) + os.chown(working, 1001, 1001) + working.chmod(0o700) + report = working / "results.xml" + command = [ + sys.executable, + "-I", + "/tests/test_driver.py", + *contract["test_paths"], + "-q", + "--tb=short", + "-p", + "no:cacheprovider", + f"--junitxml={report}", + ] + with (logs / "stdout.txt").open("w") as stdout, (logs / "stderr.txt").open("w") as stderr: + process = subprocess.Popen( + command, + cwd="/workspace", + stdout=stdout, + stderr=stderr, + user=1001, + group=1001, + extra_groups=[], + start_new_session=True, + env=child_environment(temporary), + ) + try: + code = process.wait(timeout=contract["timeout_sec"]) + finally: + # Terminate descendants too: they must not keep modifying the + # child-owned report while the trusted parent checks it. + try: + os.killpg(process.pid, signal.SIGKILL) + except ProcessLookupError: + pass + process.wait() + if report.is_symlink() or not report.is_file() or report.stat().st_size > 16 * 1024 * 1024: + (logs / "result.json").write_text( + json.dumps({"passed": False, "returncode": code, "reason": "invalid_report"}) + ) + return + text = report.read_text() + (logs / "results.xml").write_text(text) + try: + parsed = parser.parse_junit(text, returncode=code) + except ValueError as exc: + (logs / "result.json").write_text( + json.dumps({"passed": False, "returncode": code, "reason": str(exc)}) + ) + return + expected = set(contract["expected_passes"]) + passed = code == 0 and bool(expected) and parsed.passed == expected + (logs / "result.json").write_text( + json.dumps({"passed": passed, "returncode": code, "statuses": parsed.statuses}) + ) + reward.write_text("1\n" if passed else "0\n") + + +if __name__ == "__main__": + main() diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/bug-report.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/bug-report.yml new file mode 100644 index 0000000000000000000000000000000000000000..a0517725284e6062287e08dad3495d94b0bd0481 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/bug-report.yml @@ -0,0 +1,110 @@ +name: "\U0001F41B Bug Report" +description: Report a bug on Diffusers +labels: [ "bug" ] +body: + - type: markdown + attributes: + value: | + Thanks a lot for taking the time to file this issue 🤗. + Issues do not only help to improve the library, but also publicly document common problems, questions, workflows for the whole community! + Thus, issues are of the same importance as pull requests when contributing to this library ❤️. + In order to make your issue as **useful for the community as possible**, let's try to stick to some simple guidelines: + - 1. Please try to be as precise and concise as possible. + *Give your issue a fitting title. Assume that someone which very limited knowledge of Diffusers can understand your issue. Add links to the source code, documentation other issues, pull requests etc...* + - 2. If your issue is about something not working, **always** provide a reproducible code snippet. The reader should be able to reproduce your issue by **only copy-pasting your code snippet into a Python shell**. + *The community cannot solve your issue if it cannot reproduce it. If your bug is related to training, add your training script and make everything needed to train public. Otherwise, just add a simple Python code snippet.* + - 3. Add the **minimum** amount of code / context that is needed to understand, reproduce your issue. + *Make the life of maintainers easy. `diffusers` is getting many issues every day. Make sure your issue is about one bug and one bug only. Make sure you add only the context, code needed to understand your issues - nothing more. Generally, every issue is a way of documenting this library, try to make it a good documentation entry.* + - 4. For issues related to community pipelines (i.e., the pipelines located in the `examples/community` folder), please tag the author of the pipeline in your issue thread as those pipelines are not maintained. + - type: markdown + attributes: + value: | + For more in-detail information on how to write good issues you can have a look [here](https://huggingface.co/course/chapter8/5?fw=pt). + - type: textarea + id: bug-description + attributes: + label: Describe the bug + description: A clear and concise description of what the bug is. If you intend to submit a pull request for this issue, tell us in the description. Thanks! + placeholder: Bug description + validations: + required: true + - type: textarea + id: reproduction + attributes: + label: Reproduction + description: Please provide a minimal reproducible code which we can copy/paste and reproduce the issue. + placeholder: Reproduction + validations: + required: true + - type: textarea + id: logs + attributes: + label: Logs + description: "Please include the Python logs if you can." + render: shell + - type: textarea + id: system-info + attributes: + label: System Info + description: Please share your system info with us. You can run the command `diffusers-cli env` and copy-paste its output below. + placeholder: Diffusers version, platform, Python version, ... + validations: + required: true + - type: textarea + id: who-can-help + attributes: + label: Who can help? + description: | + Your issue will be replied to more quickly if you can figure out the right person to tag with @. + If you know how to use git blame, that is the easiest way, otherwise, here is a rough guide of **who to tag**. + + All issues are read by one of the core maintainers, so if you don't know who to tag, just leave this blank and + a core maintainer will ping the right person. + + Please tag a maximum of 2 people. + + Questions on DiffusionPipeline (Saving, Loading, From pretrained, ...): @sayakpaul @DN6 + + Questions on pipelines: + - Stable Diffusion @yiyixuxu @asomoza + - Stable Diffusion XL @yiyixuxu @sayakpaul @DN6 + - Stable Diffusion 3: @yiyixuxu @sayakpaul @DN6 @asomoza + - Kandinsky @yiyixuxu + - ControlNet @sayakpaul @yiyixuxu @DN6 + - T2I Adapter @sayakpaul @yiyixuxu @DN6 + - IF @DN6 + - Text-to-Video / Video-to-Video @DN6 @a-r-r-o-w + - Wuerstchen @DN6 + - Other: @yiyixuxu @DN6 + - Improving generation quality: @asomoza + + Questions on models: + - UNet @DN6 @yiyixuxu @sayakpaul + - VAE @sayakpaul @DN6 @yiyixuxu + - Transformers/Attention @DN6 @yiyixuxu @sayakpaul + + Questions on single file checkpoints: @DN6 + + Questions on Schedulers: @yiyixuxu + + Questions on LoRA: @sayakpaul + + Questions on Textual Inversion: @sayakpaul + + Questions on Training: + - DreamBooth @sayakpaul + - Text-to-Image Fine-tuning @sayakpaul + - Textual Inversion @sayakpaul + - ControlNet @sayakpaul + + Questions on Tests: @DN6 @sayakpaul @yiyixuxu + + Questions on Documentation: @stevhliu + + Questions on JAX- and MPS-related things: @pcuenca + + Questions on audio pipelines: @sanchit-gandhi + + + + placeholder: "@Username ..." diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/config.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/config.yml new file mode 100644 index 0000000000000000000000000000000000000000..e81992fe3c69b65f58f627252ffa6569d1cd67e2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/config.yml @@ -0,0 +1,4 @@ +contact_links: + - name: Questions / Discussions + url: https://github.com/huggingface/diffusers/discussions + about: General usage questions and community discussions diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/feature_request.md b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/feature_request.md new file mode 100644 index 0000000000000000000000000000000000000000..42f93232c1de7c73dcd90cdb6b0733bbb4461508 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/feature_request.md @@ -0,0 +1,20 @@ +--- +name: "\U0001F680 Feature Request" +about: Suggest an idea for this project +title: '' +labels: '' +assignees: '' + +--- + +**Is your feature request related to a problem? Please describe.** +A clear and concise description of what the problem is. Ex. I'm always frustrated when [...]. + +**Describe the solution you'd like.** +A clear and concise description of what you want to happen. + +**Describe alternatives you've considered.** +A clear and concise description of any alternative solutions or features you've considered. + +**Additional context.** +Add any other context or screenshots about the feature request here. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/feedback.md b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/feedback.md new file mode 100644 index 0000000000000000000000000000000000000000..25808b6575a405694f64dbf1b5a0ece8e0fcd2e2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/feedback.md @@ -0,0 +1,12 @@ +--- +name: "💬 Feedback about API Design" +about: Give feedback about the current API design +title: '' +labels: '' +assignees: '' + +--- + +**What API design would you like to have changed or added to the library? Why?** + +**What use case would this enable or better enable? Can you give us a code example?** diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/new-model-addition.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/new-model-addition.yml new file mode 100644 index 0000000000000000000000000000000000000000..432e287dd3348965466a696ee5e01a187f179ee5 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/new-model-addition.yml @@ -0,0 +1,31 @@ +name: "\U0001F31F New Model/Pipeline/Scheduler Addition" +description: Submit a proposal/request to implement a new diffusion model/pipeline/scheduler +labels: [ "New model/pipeline/scheduler" ] + +body: + - type: textarea + id: description-request + validations: + required: true + attributes: + label: Model/Pipeline/Scheduler description + description: | + Put any and all important information relative to the model/pipeline/scheduler + + - type: checkboxes + id: information-tasks + attributes: + label: Open source status + description: | + Please note that if the model implementation isn't available or if the weights aren't open-source, we are less likely to implement it in `diffusers`. + options: + - label: "The model implementation is available." + - label: "The model weights are available (Only relevant if addition is not a scheduler)." + + - type: textarea + id: additional-info + attributes: + label: Provide useful links for the implementation + description: | + Please provide information regarding the implementation, the weights, and the authors. + Please mention the authors by @gh-username if you're aware of their usernames. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/remote-vae-pilot-feedback.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/remote-vae-pilot-feedback.yml new file mode 100644 index 0000000000000000000000000000000000000000..c94d3bed97380f475a5a71c47f0f4a0870753620 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/remote-vae-pilot-feedback.yml @@ -0,0 +1,38 @@ +name: "\U0001F31F Remote VAE" +description: Feedback for remote VAE pilot +labels: [ "Remote VAE" ] + +body: + - type: textarea + id: positive + validations: + required: true + attributes: + label: Did you like the remote VAE solution? + description: | + If you liked it, we would appreciate it if you could elaborate what you liked. + + - type: textarea + id: feedback + validations: + required: true + attributes: + label: What can be improved about the current solution? + description: | + Let us know the things you would like to see improved. Note that we will work optimizing the solution once the pilot is over and we have usage. + + - type: textarea + id: others + validations: + required: true + attributes: + label: What other VAEs you would like to see if the pilot goes well? + description: | + Provide a list of the VAEs you would like to see in the future if the pilot goes well. + + - type: textarea + id: additional-info + attributes: + label: Notify the members of the team + description: | + Tag the following folks when submitting this feedback: @hlky @sayakpaul diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/translate.md b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/translate.md new file mode 100644 index 0000000000000000000000000000000000000000..3471ec9640d727e7cdf223852d2012834660e88a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/ISSUE_TEMPLATE/translate.md @@ -0,0 +1,29 @@ +--- +name: 🌐 Translating a New Language? +about: Start a new translation effort in your language +title: '[] Translating docs to ' +labels: WIP +assignees: '' + +--- + + + +Hi! + +Let's bring the documentation to all the -speaking community 🌐. + +Who would want to translate? Please follow the 🤗 [TRANSLATING guide](https://github.com/huggingface/diffusers/blob/main/docs/TRANSLATING.md). Here is a list of the files ready for translation. Let us know in this issue if you'd like to translate any, and we'll add your name to the list. + +Some notes: + +* Please translate using an informal tone (imagine you are talking with a friend about Diffusers 🤗). +* Please translate in a gender-neutral way. +* Add your translations to the folder called `` inside the [source folder](https://github.com/huggingface/diffusers/tree/main/docs/source). +* Register your translation in `/_toctree.yml`; please follow the order of the [English version](https://github.com/huggingface/diffusers/blob/main/docs/source/en/_toctree.yml). +* Once you're finished, open a pull request and tag this issue by including #issue-number in the description, where issue-number is the number of this issue. Please ping @stevhliu for review. +* 🙋 If you'd like others to help you with the translation, you can also post in the 🤗 [forums](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63). + +Thank you so much for your help! 🤗 diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/PULL_REQUEST_TEMPLATE.md b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/PULL_REQUEST_TEMPLATE.md new file mode 100644 index 0000000000000000000000000000000000000000..e4b2b45a4ecde200e65e3a2e16ac0cdb0b87d7c3 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/PULL_REQUEST_TEMPLATE.md @@ -0,0 +1,61 @@ +# What does this PR do? + + + + + +Fixes # (issue) + + +## Before submitting +- [ ] This PR fixes a typo or improves the docs (you can dismiss the other checks if that's the case). +- [ ] Did you read the [contributor guideline](https://github.com/huggingface/diffusers/blob/main/CONTRIBUTING.md)? +- [ ] Did you read our [philosophy doc](https://github.com/huggingface/diffusers/blob/main/PHILOSOPHY.md) (important for complex PRs)? +- [ ] Was this discussed/approved via a GitHub issue or the [forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63)? Please add a link to it if that's the case. +- [ ] Did you make sure to update the documentation with your changes? Here are the + [documentation guidelines](https://github.com/huggingface/diffusers/tree/main/docs), and + [here are tips on formatting docstrings](https://github.com/huggingface/diffusers/tree/main/docs#writing-source-documentation). +- [ ] Did you write any new necessary tests? + + +## Who can review? + +Anyone in the community is free to review the PR once the tests have passed. Feel free to tag +members/contributors who may be interested in your PR. + + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/actions/setup-miniconda/action.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/actions/setup-miniconda/action.yml new file mode 100644 index 0000000000000000000000000000000000000000..b1f4f194bfe1fd14e03239269e466e7978e3d5c5 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/actions/setup-miniconda/action.yml @@ -0,0 +1,146 @@ +name: Set up conda environment for testing + +description: Sets up miniconda in your ${RUNNER_TEMP} environment and gives you the ${CONDA_RUN} environment variable so you don't have to worry about polluting non-empeheral runners anymore + +inputs: + python-version: + description: If set to any value, don't use sudo to clean the workspace + required: false + type: string + default: "3.9" + miniconda-version: + description: Miniconda version to install + required: false + type: string + default: "4.12.0" + environment-file: + description: Environment file to install dependencies from + required: false + type: string + default: "" + +runs: + using: composite + steps: + # Use the same trick from https://github.com/marketplace/actions/setup-miniconda + # to refresh the cache daily. This is kind of optional though + - name: Get date + id: get-date + shell: bash + run: echo "today=$(/bin/date -u '+%Y%m%d')d" >> $GITHUB_OUTPUT + - name: Setup miniconda cache + id: miniconda-cache + uses: actions/cache@v2 + with: + path: ${{ runner.temp }}/miniconda + key: miniconda-${{ runner.os }}-${{ runner.arch }}-${{ inputs.python-version }}-${{ steps.get-date.outputs.today }} + - name: Install miniconda (${{ inputs.miniconda-version }}) + if: steps.miniconda-cache.outputs.cache-hit != 'true' + env: + MINICONDA_VERSION: ${{ inputs.miniconda-version }} + shell: bash -l {0} + run: | + MINICONDA_INSTALL_PATH="${RUNNER_TEMP}/miniconda" + mkdir -p "${MINICONDA_INSTALL_PATH}" + case ${RUNNER_OS}-${RUNNER_ARCH} in + Linux-X64) + MINICONDA_ARCH="Linux-x86_64" + ;; + macOS-ARM64) + MINICONDA_ARCH="MacOSX-arm64" + ;; + macOS-X64) + MINICONDA_ARCH="MacOSX-x86_64" + ;; + *) + echo "::error::Platform ${RUNNER_OS}-${RUNNER_ARCH} currently unsupported using this action" + exit 1 + ;; + esac + MINICONDA_URL="https://repo.anaconda.com/miniconda/Miniconda3-py39_${MINICONDA_VERSION}-${MINICONDA_ARCH}.sh" + curl -fsSL "${MINICONDA_URL}" -o "${MINICONDA_INSTALL_PATH}/miniconda.sh" + bash "${MINICONDA_INSTALL_PATH}/miniconda.sh" -b -u -p "${MINICONDA_INSTALL_PATH}" + rm -rf "${MINICONDA_INSTALL_PATH}/miniconda.sh" + - name: Update GitHub path to include miniconda install + shell: bash + run: | + MINICONDA_INSTALL_PATH="${RUNNER_TEMP}/miniconda" + echo "${MINICONDA_INSTALL_PATH}/bin" >> $GITHUB_PATH + - name: Setup miniconda env cache (with env file) + id: miniconda-env-cache-env-file + if: ${{ runner.os }} == 'macOS' && ${{ inputs.environment-file }} != '' + uses: actions/cache@v2 + with: + path: ${{ runner.temp }}/conda-python-${{ inputs.python-version }} + key: miniconda-env-${{ runner.os }}-${{ runner.arch }}-${{ inputs.python-version }}-${{ steps.get-date.outputs.today }}-${{ hashFiles(inputs.environment-file) }} + - name: Setup miniconda env cache (without env file) + id: miniconda-env-cache + if: ${{ runner.os }} == 'macOS' && ${{ inputs.environment-file }} == '' + uses: actions/cache@v2 + with: + path: ${{ runner.temp }}/conda-python-${{ inputs.python-version }} + key: miniconda-env-${{ runner.os }}-${{ runner.arch }}-${{ inputs.python-version }}-${{ steps.get-date.outputs.today }} + - name: Setup conda environment with python (v${{ inputs.python-version }}) + if: steps.miniconda-env-cache-env-file.outputs.cache-hit != 'true' && steps.miniconda-env-cache.outputs.cache-hit != 'true' + shell: bash + env: + PYTHON_VERSION: ${{ inputs.python-version }} + ENV_FILE: ${{ inputs.environment-file }} + run: | + CONDA_BASE_ENV="${RUNNER_TEMP}/conda-python-${PYTHON_VERSION}" + ENV_FILE_FLAG="" + if [[ -f "${ENV_FILE}" ]]; then + ENV_FILE_FLAG="--file ${ENV_FILE}" + elif [[ -n "${ENV_FILE}" ]]; then + echo "::warning::Specified env file (${ENV_FILE}) not found, not going to include it" + fi + conda create \ + --yes \ + --prefix "${CONDA_BASE_ENV}" \ + "python=${PYTHON_VERSION}" \ + ${ENV_FILE_FLAG} \ + cmake=3.22 \ + conda-build=3.21 \ + ninja=1.10 \ + pkg-config=0.29 \ + wheel=0.37 + - name: Clone the base conda environment and update GitHub env + shell: bash + env: + PYTHON_VERSION: ${{ inputs.python-version }} + CONDA_BASE_ENV: ${{ runner.temp }}/conda-python-${{ inputs.python-version }} + run: | + CONDA_ENV="${RUNNER_TEMP}/conda_environment_${GITHUB_RUN_ID}" + conda create \ + --yes \ + --prefix "${CONDA_ENV}" \ + --clone "${CONDA_BASE_ENV}" + # TODO: conda-build could not be cloned because it hardcodes the path, so it + # could not be cached + conda install --yes -p ${CONDA_ENV} conda-build=3.21 + echo "CONDA_ENV=${CONDA_ENV}" >> "${GITHUB_ENV}" + echo "CONDA_RUN=conda run -p ${CONDA_ENV} --no-capture-output" >> "${GITHUB_ENV}" + echo "CONDA_BUILD=conda run -p ${CONDA_ENV} conda-build" >> "${GITHUB_ENV}" + echo "CONDA_INSTALL=conda install -p ${CONDA_ENV}" >> "${GITHUB_ENV}" + - name: Get disk space usage and throw an error for low disk space + shell: bash + run: | + echo "Print the available disk space for manual inspection" + df -h + # Set the minimum requirement space to 4GB + MINIMUM_AVAILABLE_SPACE_IN_GB=4 + MINIMUM_AVAILABLE_SPACE_IN_KB=$(($MINIMUM_AVAILABLE_SPACE_IN_GB * 1024 * 1024)) + # Use KB to avoid floating point warning like 3.1GB + df -k | tr -s ' ' | cut -d' ' -f 4,9 | while read -r LINE; + do + AVAIL=$(echo $LINE | cut -f1 -d' ') + MOUNT=$(echo $LINE | cut -f2 -d' ') + if [ "$MOUNT" = "/" ]; then + if [ "$AVAIL" -lt "$MINIMUM_AVAILABLE_SPACE_IN_KB" ]; then + echo "There is only ${AVAIL}KB free space left in $MOUNT, which is less than the minimum requirement of ${MINIMUM_AVAILABLE_SPACE_IN_KB}KB. Please help create an issue to PyTorch Release Engineering via https://github.com/pytorch/test-infra/issues and provide the link to the workflow run." + exit 1; + else + echo "There is ${AVAIL}KB free space left in $MOUNT, continue" + fi + fi + done diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/benchmark.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/benchmark.yml new file mode 100644 index 0000000000000000000000000000000000000000..696097fd5473d5fa0aa71ed5dc918894fce439a1 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/benchmark.yml @@ -0,0 +1,68 @@ +name: Benchmarking tests + +on: + workflow_dispatch: + schedule: + - cron: "30 1 1,15 * *" # every 2 weeks on the 1st and the 15th of every month at 1:30 AM + +env: + DIFFUSERS_IS_CI: yes + HF_HUB_ENABLE_HF_TRANSFER: 1 + HF_HOME: /mnt/cache + OMP_NUM_THREADS: 8 + MKL_NUM_THREADS: 8 + +jobs: + torch_pipelines_cuda_benchmark_tests: + env: + SLACK_WEBHOOK_URL: ${{ secrets.SLACK_WEBHOOK_URL_BENCHMARK }} + name: Torch Core Pipelines CUDA Benchmarking Tests + strategy: + fail-fast: false + max-parallel: 1 + runs-on: + group: aws-g6-4xlarge-plus + container: + image: diffusers/diffusers-pytorch-cuda + options: --shm-size "16gb" --ipc host --gpus 0 + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + - name: NVIDIA-SMI + run: | + nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + python -m uv pip install pandas peft + python -m uv pip uninstall transformers && python -m uv pip install transformers==4.48.0 + - name: Environment + run: | + python utils/print_env.py + - name: Diffusers Benchmarking + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_BOT_TOKEN }} + BASE_PATH: benchmark_outputs + run: | + export TOTAL_GPU_MEMORY=$(python -c "import torch; print(torch.cuda.get_device_properties(0).total_memory / (1024**3))") + cd benchmarks && mkdir ${BASE_PATH} && python run_all.py && python push_results.py + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: benchmark_test_reports + path: benchmarks/benchmark_outputs + + - name: Report success status + if: ${{ success() }} + run: | + pip install requests && python utils/notify_benchmarking_status.py --status=success + + - name: Report failure status + if: ${{ failure() }} + run: | + pip install requests && python utils/notify_benchmarking_status.py --status=failure \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/build_docker_images.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/build_docker_images.yml new file mode 100644 index 0000000000000000000000000000000000000000..838f241ddc7dcf7d4b3860a2b9e63b974a067961 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/build_docker_images.yml @@ -0,0 +1,111 @@ +name: Test, build, and push Docker images + +on: + pull_request: # During PRs, we just check if the changes Dockerfiles can be successfully built + branches: + - main + paths: + - "docker/**" + workflow_dispatch: + schedule: + - cron: "0 0 * * *" # every day at midnight + +concurrency: + group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }} + cancel-in-progress: true + +env: + REGISTRY: diffusers + CI_SLACK_CHANNEL: ${{ secrets.CI_DOCKER_CHANNEL }} + +jobs: + test-build-docker-images: + runs-on: + group: aws-general-8-plus + if: github.event_name == 'pull_request' + steps: + - name: Set up Docker Buildx + uses: docker/setup-buildx-action@v1 + + - name: Check out code + uses: actions/checkout@v3 + + - name: Find Changed Dockerfiles + id: file_changes + uses: jitterbit/get-changed-files@v1 + with: + format: "space-delimited" + token: ${{ secrets.GITHUB_TOKEN }} + + - name: Build Changed Docker Images + env: + CHANGED_FILES: ${{ steps.file_changes.outputs.all }} + run: | + echo "$CHANGED_FILES" + for FILE in $CHANGED_FILES; do + # skip anything that isn't still on disk + if [[ ! -f "$FILE" ]]; then + echo "Skipping removed file $FILE" + continue + fi + if [[ "$FILE" == docker/*Dockerfile ]]; then + DOCKER_PATH="${FILE%/Dockerfile}" + DOCKER_TAG=$(basename "$DOCKER_PATH") + echo "Building Docker image for $DOCKER_TAG" + docker build -t "$DOCKER_TAG" "$DOCKER_PATH" + fi + done + if: steps.file_changes.outputs.all != '' + + build-and-push-docker-images: + runs-on: + group: aws-general-8-plus + if: github.event_name != 'pull_request' + + permissions: + contents: read + packages: write + + strategy: + fail-fast: false + matrix: + image-name: + - diffusers-pytorch-cpu + - diffusers-pytorch-cuda + - diffusers-pytorch-cuda + - diffusers-pytorch-xformers-cuda + - diffusers-pytorch-minimum-cuda + - diffusers-flax-cpu + - diffusers-flax-tpu + - diffusers-onnxruntime-cpu + - diffusers-onnxruntime-cuda + - diffusers-doc-builder + + steps: + - name: Checkout repository + uses: actions/checkout@v3 + - name: Set up Docker Buildx + uses: docker/setup-buildx-action@v1 + - name: Login to Docker Hub + uses: docker/login-action@v2 + with: + username: ${{ env.REGISTRY }} + password: ${{ secrets.DOCKERHUB_TOKEN }} + - name: Build and push + uses: docker/build-push-action@v3 + with: + no-cache: true + context: ./docker/${{ matrix.image-name }} + push: true + tags: ${{ env.REGISTRY }}/${{ matrix.image-name }}:latest + + - name: Post to a Slack channel + id: slack + uses: huggingface/hf-workflows/.github/actions/post-slack@main + with: + # Slack channel id, channel name, or user id to post message. + # See also: https://api.slack.com/methods/chat.postMessage#channels + slack_channel: ${{ env.CI_SLACK_CHANNEL }} + title: "🤗 Results of the ${{ matrix.image-name }} Docker Image build" + status: ${{ job.status }} + slack_token: ${{ secrets.SLACK_CIFEEDBACK_BOT_TOKEN }} diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/build_documentation.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/build_documentation.yml new file mode 100644 index 0000000000000000000000000000000000000000..6d4193e3cccc42e6824e9f0881a6b3e50bfa7173 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/build_documentation.yml @@ -0,0 +1,27 @@ +name: Build documentation + +on: + push: + branches: + - main + - doc-builder* + - v*-release + - v*-patch + paths: + - "src/diffusers/**.py" + - "examples/**" + - "docs/**" + +jobs: + build: + uses: huggingface/doc-builder/.github/workflows/build_main_documentation.yml@main + with: + commit_sha: ${{ github.sha }} + install_libgl1: true + package: diffusers + notebook_folder: diffusers_doc + languages: en ko zh ja pt + custom_container: diffusers/diffusers-doc-builder + secrets: + token: ${{ secrets.HUGGINGFACE_PUSH }} + hf_token: ${{ secrets.HF_DOC_BUILD_PUSH }} diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/build_pr_documentation.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/build_pr_documentation.yml new file mode 100644 index 0000000000000000000000000000000000000000..52e0757331639c7335132766cfc2afb2d74e0368 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/build_pr_documentation.yml @@ -0,0 +1,23 @@ +name: Build PR Documentation + +on: + pull_request: + paths: + - "src/diffusers/**.py" + - "examples/**" + - "docs/**" + +concurrency: + group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }} + cancel-in-progress: true + +jobs: + build: + uses: huggingface/doc-builder/.github/workflows/build_pr_documentation.yml@main + with: + commit_sha: ${{ github.event.pull_request.head.sha }} + pr_number: ${{ github.event.number }} + install_libgl1: true + package: diffusers + languages: en ko zh ja pt + custom_container: diffusers/diffusers-doc-builder diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/mirror_community_pipeline.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/mirror_community_pipeline.yml new file mode 100644 index 0000000000000000000000000000000000000000..f6eff1bbd8f05fe937c72453d04b430b6882628b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/mirror_community_pipeline.yml @@ -0,0 +1,102 @@ +name: Mirror Community Pipeline + +on: + # Push changes on the main branch + push: + branches: + - main + paths: + - 'examples/community/**.py' + + # And on tag creation (e.g. `v0.28.1`) + tags: + - '*' + + # Manual trigger with ref input + workflow_dispatch: + inputs: + ref: + description: "Either 'main' or a tag ref" + required: true + default: 'main' + +jobs: + mirror_community_pipeline: + env: + SLACK_WEBHOOK_URL: ${{ secrets.SLACK_WEBHOOK_URL_COMMUNITY_MIRROR }} + + runs-on: ubuntu-22.04 + steps: + # Checkout to correct ref + # If workflow dispatch + # If ref is 'main', set: + # CHECKOUT_REF=refs/heads/main + # PATH_IN_REPO=main + # Else it must be a tag. Set: + # CHECKOUT_REF=refs/tags/{tag} + # PATH_IN_REPO={tag} + # If not workflow dispatch + # If ref is 'refs/heads/main' => set 'main' + # Else it must be a tag => set {tag} + - name: Set checkout_ref and path_in_repo + run: | + if [ "${{ github.event_name }}" == "workflow_dispatch" ]; then + if [ -z "${{ github.event.inputs.ref }}" ]; then + echo "Error: Missing ref input" + exit 1 + elif [ "${{ github.event.inputs.ref }}" == "main" ]; then + echo "CHECKOUT_REF=refs/heads/main" >> $GITHUB_ENV + echo "PATH_IN_REPO=main" >> $GITHUB_ENV + else + echo "CHECKOUT_REF=refs/tags/${{ github.event.inputs.ref }}" >> $GITHUB_ENV + echo "PATH_IN_REPO=${{ github.event.inputs.ref }}" >> $GITHUB_ENV + fi + elif [ "${{ github.ref }}" == "refs/heads/main" ]; then + echo "CHECKOUT_REF=${{ github.ref }}" >> $GITHUB_ENV + echo "PATH_IN_REPO=main" >> $GITHUB_ENV + else + # e.g. refs/tags/v0.28.1 -> v0.28.1 + echo "CHECKOUT_REF=${{ github.ref }}" >> $GITHUB_ENV + echo "PATH_IN_REPO=$(echo ${{ github.ref }} | sed 's/^refs\/tags\///')" >> $GITHUB_ENV + fi + - name: Print env vars + run: | + echo "CHECKOUT_REF: ${{ env.CHECKOUT_REF }}" + echo "PATH_IN_REPO: ${{ env.PATH_IN_REPO }}" + - uses: actions/checkout@v3 + with: + ref: ${{ env.CHECKOUT_REF }} + + # Setup + install dependencies + - name: Set up Python + uses: actions/setup-python@v4 + with: + python-version: "3.10" + - name: Install dependencies + run: | + python -m pip install --upgrade pip + pip install --upgrade huggingface_hub + + # Check secret is set + - name: whoami + run: huggingface-cli whoami + env: + HF_TOKEN: ${{ secrets.HF_TOKEN_MIRROR_COMMUNITY_PIPELINES }} + + # Push to HF! (under subfolder based on checkout ref) + # https://huggingface.co/datasets/diffusers/community-pipelines-mirror + - name: Mirror community pipeline to HF + run: huggingface-cli upload diffusers/community-pipelines-mirror ./examples/community ${PATH_IN_REPO} --repo-type dataset + env: + PATH_IN_REPO: ${{ env.PATH_IN_REPO }} + HF_TOKEN: ${{ secrets.HF_TOKEN_MIRROR_COMMUNITY_PIPELINES }} + + - name: Report success status + if: ${{ success() }} + run: | + pip install requests && python utils/notify_community_pipelines_mirror.py --status=success + + - name: Report failure status + if: ${{ failure() }} + run: | + pip install requests && python utils/notify_community_pipelines_mirror.py --status=failure \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/nightly_tests.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/nightly_tests.yml new file mode 100644 index 0000000000000000000000000000000000000000..b4c973711e9d7d94732d0a457c21c0749b769dca --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/nightly_tests.yml @@ -0,0 +1,697 @@ +name: Nightly and release tests on main/release branch + +on: + workflow_dispatch: + schedule: + - cron: "0 0 * * *" # every day at midnight + +env: + DIFFUSERS_IS_CI: yes + HF_HUB_ENABLE_HF_TRANSFER: 1 + OMP_NUM_THREADS: 8 + MKL_NUM_THREADS: 8 + PYTEST_TIMEOUT: 600 + RUN_SLOW: yes + RUN_NIGHTLY: yes + PIPELINE_USAGE_CUTOFF: 5000 + SLACK_API_TOKEN: ${{ secrets.SLACK_CIFEEDBACK_BOT_TOKEN }} + +jobs: + setup_torch_cuda_pipeline_matrix: + name: Setup Torch Pipelines CUDA Slow Tests Matrix + runs-on: + group: aws-general-8-plus + container: + image: diffusers/diffusers-pytorch-cpu + outputs: + pipeline_test_matrix: ${{ steps.fetch_pipeline_matrix.outputs.pipeline_test_matrix }} + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + - name: Install dependencies + run: | + pip install -e .[test] + pip install huggingface_hub + - name: Fetch Pipeline Matrix + id: fetch_pipeline_matrix + run: | + matrix=$(python utils/fetch_torch_cuda_pipeline_test_matrix.py) + echo $matrix + echo "pipeline_test_matrix=$matrix" >> $GITHUB_OUTPUT + + - name: Pipeline Tests Artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: test-pipelines.json + path: reports + + run_nightly_tests_for_torch_pipelines: + name: Nightly Torch Pipelines CUDA Tests + needs: setup_torch_cuda_pipeline_matrix + strategy: + fail-fast: false + max-parallel: 8 + matrix: + module: ${{ fromJson(needs.setup_torch_cuda_pipeline_matrix.outputs.pipeline_test_matrix) }} + runs-on: + group: aws-g4dn-2xlarge + container: + image: diffusers/diffusers-pytorch-cuda + options: --shm-size "16gb" --ipc host --gpus 0 + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + - name: NVIDIA-SMI + run: nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + python -m uv pip install pytest-reportlog + - name: Environment + run: | + python utils/print_env.py + - name: Pipeline CUDA Test + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "not Flax and not Onnx" \ + --make-reports=tests_pipeline_${{ matrix.module }}_cuda \ + --report-log=tests_pipeline_${{ matrix.module }}_cuda.log \ + tests/pipelines/${{ matrix.module }} + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_pipeline_${{ matrix.module }}_cuda_stats.txt + cat reports/tests_pipeline_${{ matrix.module }}_cuda_failures_short.txt + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: pipeline_${{ matrix.module }}_test_reports + path: reports + - name: Generate Report and Notify Channel + if: always() + run: | + pip install slack_sdk tabulate + python utils/log_reports.py >> $GITHUB_STEP_SUMMARY + + run_nightly_tests_for_other_torch_modules: + name: Nightly Torch CUDA Tests + runs-on: + group: aws-g4dn-2xlarge + container: + image: diffusers/diffusers-pytorch-cuda + options: --shm-size "16gb" --ipc host --gpus 0 + defaults: + run: + shell: bash + strategy: + fail-fast: false + max-parallel: 2 + matrix: + module: [models, schedulers, lora, others, single_file, examples] + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + python -m uv pip install peft@git+https://github.com/huggingface/peft.git + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + python -m uv pip install pytest-reportlog + - name: Environment + run: python utils/print_env.py + + - name: Run nightly PyTorch CUDA tests for non-pipeline modules + if: ${{ matrix.module != 'examples'}} + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + RUN_COMPILE: yes + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "not Flax and not Onnx" \ + --make-reports=tests_torch_${{ matrix.module }}_cuda \ + --report-log=tests_torch_${{ matrix.module }}_cuda.log \ + tests/${{ matrix.module }} + + - name: Run nightly example tests with Torch + if: ${{ matrix.module == 'examples' }} + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v --make-reports=examples_torch_cuda \ + --report-log=examples_torch_cuda.log \ + examples/ + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_torch_${{ matrix.module }}_cuda_stats.txt + cat reports/tests_torch_${{ matrix.module }}_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_${{ matrix.module }}_cuda_test_reports + path: reports + + - name: Generate Report and Notify Channel + if: always() + run: | + pip install slack_sdk tabulate + python utils/log_reports.py >> $GITHUB_STEP_SUMMARY + + run_torch_compile_tests: + name: PyTorch Compile CUDA tests + + runs-on: + group: aws-g4dn-2xlarge + + container: + image: diffusers/diffusers-pytorch-cuda + options: --gpus 0 --shm-size "16gb" --ipc host + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: NVIDIA-SMI + run: | + nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test,training] + - name: Environment + run: | + python utils/print_env.py + - name: Run torch compile tests on GPU + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + RUN_COMPILE: yes + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile -s -v -k "compile" --make-reports=tests_torch_compile_cuda tests/ + - name: Failure short reports + if: ${{ failure() }} + run: cat reports/tests_torch_compile_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_compile_test_reports + path: reports + + - name: Generate Report and Notify Channel + if: always() + run: | + pip install slack_sdk tabulate + python utils/log_reports.py >> $GITHUB_STEP_SUMMARY + + run_big_gpu_torch_tests: + name: Torch tests on big GPU + strategy: + fail-fast: false + max-parallel: 2 + runs-on: + group: aws-g6e-xlarge-plus + container: + image: diffusers/diffusers-pytorch-cuda + options: --shm-size "16gb" --ipc host --gpus 0 + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + - name: NVIDIA-SMI + run: nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + python -m uv pip install peft@git+https://github.com/huggingface/peft.git + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + python -m uv pip install pytest-reportlog + - name: Environment + run: | + python utils/print_env.py + - name: Selected Torch CUDA Test on big GPU + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + BIG_GPU_MEMORY: 40 + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -m "big_gpu_with_torch_cuda" \ + --make-reports=tests_big_gpu_torch_cuda \ + --report-log=tests_big_gpu_torch_cuda.log \ + tests/ + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_big_gpu_torch_cuda_stats.txt + cat reports/tests_big_gpu_torch_cuda_failures_short.txt + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_cuda_big_gpu_test_reports + path: reports + - name: Generate Report and Notify Channel + if: always() + run: | + pip install slack_sdk tabulate + python utils/log_reports.py >> $GITHUB_STEP_SUMMARY + + torch_minimum_version_cuda_tests: + name: Torch Minimum Version CUDA Tests + runs-on: + group: aws-g4dn-2xlarge + container: + image: diffusers/diffusers-pytorch-minimum-cuda + options: --shm-size "16gb" --ipc host --gpus 0 + defaults: + run: + shell: bash + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + python -m uv pip install peft@git+https://github.com/huggingface/peft.git + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + + - name: Environment + run: | + python utils/print_env.py + + - name: Run PyTorch CUDA tests + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "not Flax and not Onnx" \ + --make-reports=tests_torch_minimum_version_cuda \ + tests/models/test_modeling_common.py \ + tests/pipelines/test_pipelines_common.py \ + tests/pipelines/test_pipeline_utils.py \ + tests/pipelines/test_pipelines.py \ + tests/pipelines/test_pipelines_auto.py \ + tests/schedulers/test_schedulers.py \ + tests/others + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_torch_minimum_version_cuda_stats.txt + cat reports/tests_torch_minimum_version_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_minimum_version_cuda_test_reports + path: reports + + run_flax_tpu_tests: + name: Nightly Flax TPU Tests + runs-on: + group: gcp-ct5lp-hightpu-8t + if: github.event_name == 'schedule' + + container: + image: diffusers/diffusers-flax-tpu + options: --shm-size "16gb" --ipc host --privileged ${{ vars.V5_LITEPOD_8_ENV}} -v /mnt/hf_cache:/mnt/hf_cache + defaults: + run: + shell: bash + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + python -m uv pip install pytest-reportlog + + - name: Environment + run: python utils/print_env.py + + - name: Run nightly Flax TPU tests + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + run: | + python -m pytest -n 0 \ + -s -v -k "Flax" \ + --make-reports=tests_flax_tpu \ + --report-log=tests_flax_tpu.log \ + tests/ + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_flax_tpu_stats.txt + cat reports/tests_flax_tpu_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: flax_tpu_test_reports + path: reports + + - name: Generate Report and Notify Channel + if: always() + run: | + pip install slack_sdk tabulate + python utils/log_reports.py >> $GITHUB_STEP_SUMMARY + + run_nightly_onnx_tests: + name: Nightly ONNXRuntime CUDA tests on Ubuntu + runs-on: + group: aws-g4dn-2xlarge + container: + image: diffusers/diffusers-onnxruntime-cuda + options: --gpus 0 --shm-size "16gb" --ipc host + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: NVIDIA-SMI + run: nvidia-smi + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + python -m uv pip install pytest-reportlog + - name: Environment + run: python utils/print_env.py + + - name: Run Nightly ONNXRuntime CUDA tests + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "Onnx" \ + --make-reports=tests_onnx_cuda \ + --report-log=tests_onnx_cuda.log \ + tests/ + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_onnx_cuda_stats.txt + cat reports/tests_onnx_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: tests_onnx_cuda_reports + path: reports + + - name: Generate Report and Notify Channel + if: always() + run: | + pip install slack_sdk tabulate + python utils/log_reports.py >> $GITHUB_STEP_SUMMARY + + run_nightly_quantization_tests: + name: Torch quantization nightly tests + strategy: + fail-fast: false + max-parallel: 2 + matrix: + config: + - backend: "bitsandbytes" + test_location: "bnb" + additional_deps: ["peft"] + - backend: "gguf" + test_location: "gguf" + additional_deps: ["peft"] + - backend: "torchao" + test_location: "torchao" + additional_deps: [] + - backend: "optimum_quanto" + test_location: "quanto" + additional_deps: [] + runs-on: + group: aws-g6e-xlarge-plus + container: + image: diffusers/diffusers-pytorch-cuda + options: --shm-size "20gb" --ipc host --gpus 0 + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + - name: NVIDIA-SMI + run: nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + python -m uv pip install -U ${{ matrix.config.backend }} + if [ "${{ join(matrix.config.additional_deps, ' ') }}" != "" ]; then + python -m uv pip install ${{ join(matrix.config.additional_deps, ' ') }} + fi + python -m uv pip install pytest-reportlog + - name: Environment + run: | + python utils/print_env.py + - name: ${{ matrix.config.backend }} quantization tests on GPU + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + BIG_GPU_MEMORY: 40 + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + --make-reports=tests_${{ matrix.config.backend }}_torch_cuda \ + --report-log=tests_${{ matrix.config.backend }}_torch_cuda.log \ + tests/quantization/${{ matrix.config.test_location }} + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_${{ matrix.config.backend }}_torch_cuda_stats.txt + cat reports/tests_${{ matrix.config.backend }}_torch_cuda_failures_short.txt + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_cuda_${{ matrix.config.backend }}_reports + path: reports + - name: Generate Report and Notify Channel + if: always() + run: | + pip install slack_sdk tabulate + python utils/log_reports.py >> $GITHUB_STEP_SUMMARY + + run_nightly_pipeline_level_quantization_tests: + name: Torch quantization nightly tests + strategy: + fail-fast: false + max-parallel: 2 + runs-on: + group: aws-g6e-xlarge-plus + container: + image: diffusers/diffusers-pytorch-cuda + options: --shm-size "20gb" --ipc host --gpus 0 + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + - name: NVIDIA-SMI + run: nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + python -m uv pip install -U bitsandbytes optimum_quanto + python -m uv pip install pytest-reportlog + - name: Environment + run: | + python utils/print_env.py + - name: Pipeline-level quantization tests on GPU + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + BIG_GPU_MEMORY: 40 + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + --make-reports=tests_pipeline_level_quant_torch_cuda \ + --report-log=tests_pipeline_level_quant_torch_cuda.log \ + tests/quantization/test_pipeline_level_quantization.py + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_pipeline_level_quant_torch_cuda_stats.txt + cat reports/tests_pipeline_level_quant_torch_cuda_failures_short.txt + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_cuda_pipeline_level_quant_reports + path: reports + - name: Generate Report and Notify Channel + if: always() + run: | + pip install slack_sdk tabulate + python utils/log_reports.py >> $GITHUB_STEP_SUMMARY + +# M1 runner currently not well supported +# TODO: (Dhruv) add these back when we setup better testing for Apple Silicon +# run_nightly_tests_apple_m1: +# name: Nightly PyTorch MPS tests on MacOS +# runs-on: [ self-hosted, apple-m1 ] +# if: github.event_name == 'schedule' +# +# steps: +# - name: Checkout diffusers +# uses: actions/checkout@v3 +# with: +# fetch-depth: 2 +# +# - name: Clean checkout +# shell: arch -arch arm64 bash {0} +# run: | +# git clean -fxd +# - name: Setup miniconda +# uses: ./.github/actions/setup-miniconda +# with: +# python-version: 3.9 +# +# - name: Install dependencies +# shell: arch -arch arm64 bash {0} +# run: | +# ${CONDA_RUN} python -m pip install --upgrade pip uv +# ${CONDA_RUN} python -m uv pip install -e [quality,test] +# ${CONDA_RUN} python -m uv pip install torch torchvision torchaudio --extra-index-url https://download.pytorch.org/whl/cpu +# ${CONDA_RUN} python -m uv pip install accelerate@git+https://github.com/huggingface/accelerate +# ${CONDA_RUN} python -m uv pip install pytest-reportlog +# - name: Environment +# shell: arch -arch arm64 bash {0} +# run: | +# ${CONDA_RUN} python utils/print_env.py +# - name: Run nightly PyTorch tests on M1 (MPS) +# shell: arch -arch arm64 bash {0} +# env: +# HF_HOME: /System/Volumes/Data/mnt/cache +# HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} +# run: | +# ${CONDA_RUN} python -m pytest -n 1 -s -v --make-reports=tests_torch_mps \ +# --report-log=tests_torch_mps.log \ +# tests/ +# - name: Failure short reports +# if: ${{ failure() }} +# run: cat reports/tests_torch_mps_failures_short.txt +# +# - name: Test suite reports artifacts +# if: ${{ always() }} +# uses: actions/upload-artifact@v4 +# with: +# name: torch_mps_test_reports +# path: reports +# +# - name: Generate Report and Notify Channel +# if: always() +# run: | +# pip install slack_sdk tabulate +# python utils/log_reports.py >> $GITHUB_STEP_SUMMARY run_nightly_tests_apple_m1: +# name: Nightly PyTorch MPS tests on MacOS +# runs-on: [ self-hosted, apple-m1 ] +# if: github.event_name == 'schedule' +# +# steps: +# - name: Checkout diffusers +# uses: actions/checkout@v3 +# with: +# fetch-depth: 2 +# +# - name: Clean checkout +# shell: arch -arch arm64 bash {0} +# run: | +# git clean -fxd +# - name: Setup miniconda +# uses: ./.github/actions/setup-miniconda +# with: +# python-version: 3.9 +# +# - name: Install dependencies +# shell: arch -arch arm64 bash {0} +# run: | +# ${CONDA_RUN} python -m pip install --upgrade pip uv +# ${CONDA_RUN} python -m uv pip install -e [quality,test] +# ${CONDA_RUN} python -m uv pip install torch torchvision torchaudio --extra-index-url https://download.pytorch.org/whl/cpu +# ${CONDA_RUN} python -m uv pip install accelerate@git+https://github.com/huggingface/accelerate +# ${CONDA_RUN} python -m uv pip install pytest-reportlog +# - name: Environment +# shell: arch -arch arm64 bash {0} +# run: | +# ${CONDA_RUN} python utils/print_env.py +# - name: Run nightly PyTorch tests on M1 (MPS) +# shell: arch -arch arm64 bash {0} +# env: +# HF_HOME: /System/Volumes/Data/mnt/cache +# HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} +# run: | +# ${CONDA_RUN} python -m pytest -n 1 -s -v --make-reports=tests_torch_mps \ +# --report-log=tests_torch_mps.log \ +# tests/ +# - name: Failure short reports +# if: ${{ failure() }} +# run: cat reports/tests_torch_mps_failures_short.txt +# +# - name: Test suite reports artifacts +# if: ${{ always() }} +# uses: actions/upload-artifact@v4 +# with: +# name: torch_mps_test_reports +# path: reports +# +# - name: Generate Report and Notify Channel +# if: always() +# run: | +# pip install slack_sdk tabulate +# python utils/log_reports.py >> $GITHUB_STEP_SUMMARY diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/notify_slack_about_release.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/notify_slack_about_release.yml new file mode 100644 index 0000000000000000000000000000000000000000..612ad4e24503a8747d58e5b3273557892782fbe8 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/notify_slack_about_release.yml @@ -0,0 +1,23 @@ +name: Notify Slack about a release + +on: + workflow_dispatch: + release: + types: [published] + +jobs: + build: + runs-on: ubuntu-22.04 + + steps: + - uses: actions/checkout@v3 + + - name: Setup Python + uses: actions/setup-python@v4 + with: + python-version: '3.8' + + - name: Notify Slack about the release + env: + SLACK_WEBHOOK_URL: ${{ secrets.SLACK_WEBHOOK_URL }} + run: pip install requests && python utils/notify_slack_about_release.py diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_dependency_test.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_dependency_test.yml new file mode 100644 index 0000000000000000000000000000000000000000..d9350c09ac427940c9160111fd6ba28a242ec5e3 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_dependency_test.yml @@ -0,0 +1,35 @@ +name: Run dependency tests + +on: + pull_request: + branches: + - main + paths: + - "src/diffusers/**.py" + push: + branches: + - main + +concurrency: + group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }} + cancel-in-progress: true + +jobs: + check_dependencies: + runs-on: ubuntu-22.04 + steps: + - uses: actions/checkout@v3 + - name: Set up Python + uses: actions/setup-python@v4 + with: + python-version: "3.8" + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m pip install --upgrade pip uv + python -m uv pip install -e . + python -m uv pip install pytest + - name: Check for soft dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + pytest tests/others/test_dependencies.py diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_flax_dependency_test.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_flax_dependency_test.yml new file mode 100644 index 0000000000000000000000000000000000000000..e091b5f2d7b3722e8108641c28f621c104b8e28f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_flax_dependency_test.yml @@ -0,0 +1,38 @@ +name: Run Flax dependency tests + +on: + pull_request: + branches: + - main + paths: + - "src/diffusers/**.py" + push: + branches: + - main + +concurrency: + group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }} + cancel-in-progress: true + +jobs: + check_flax_dependencies: + runs-on: ubuntu-22.04 + steps: + - uses: actions/checkout@v3 + - name: Set up Python + uses: actions/setup-python@v4 + with: + python-version: "3.8" + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m pip install --upgrade pip uv + python -m uv pip install -e . + python -m uv pip install "jax[cpu]>=0.2.16,!=0.3.2" + python -m uv pip install "flax>=0.4.1" + python -m uv pip install "jaxlib>=0.1.65" + python -m uv pip install pytest + - name: Check for soft dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + pytest tests/others/test_dependencies.py diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_style_bot.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_style_bot.yml new file mode 100644 index 0000000000000000000000000000000000000000..14a8f8e3d8b443647f970f87cf594809fc5ad037 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_style_bot.yml @@ -0,0 +1,17 @@ +name: PR Style Bot + +on: + issue_comment: + types: [created] + +permissions: + contents: write + pull-requests: write + +jobs: + style: + uses: huggingface/huggingface_hub/.github/workflows/style-bot-action.yml@main + with: + python_quality_dependencies: "[quality]" + secrets: + bot_token: ${{ secrets.GITHUB_TOKEN }} \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_test_fetcher.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_test_fetcher.yml new file mode 100644 index 0000000000000000000000000000000000000000..b032bb842786a73761b9ef73dfc1cc87a4ab0e26 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_test_fetcher.yml @@ -0,0 +1,177 @@ +name: Fast tests for PRs - Test Fetcher + +on: workflow_dispatch + +env: + DIFFUSERS_IS_CI: yes + OMP_NUM_THREADS: 4 + MKL_NUM_THREADS: 4 + PYTEST_TIMEOUT: 60 + +concurrency: + group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }} + cancel-in-progress: true + +jobs: + setup_pr_tests: + name: Setup PR Tests + runs-on: + group: aws-general-8-plus + container: + image: diffusers/diffusers-pytorch-cpu + options: --shm-size "16gb" --ipc host -v /mnt/hf_cache:/mnt/cache/ + defaults: + run: + shell: bash + outputs: + matrix: ${{ steps.set_matrix.outputs.matrix }} + test_map: ${{ steps.set_matrix.outputs.test_map }} + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 0 + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + - name: Environment + run: | + python utils/print_env.py + echo $(git --version) + - name: Fetch Tests + run: | + python utils/tests_fetcher.py | tee test_preparation.txt + - name: Report fetched tests + uses: actions/upload-artifact@v3 + with: + name: test_fetched + path: test_preparation.txt + - id: set_matrix + name: Create Test Matrix + # The `keys` is used as GitHub actions matrix for jobs, i.e. `models`, `pipelines`, etc. + # The `test_map` is used to get the actual identified test files under each key. + # If no test to run (so no `test_map.json` file), create a dummy map (empty matrix will fail) + run: | + if [ -f test_map.json ]; then + keys=$(python3 -c 'import json; fp = open("test_map.json"); test_map = json.load(fp); fp.close(); d = list(test_map.keys()); print(json.dumps(d))') + test_map=$(python3 -c 'import json; fp = open("test_map.json"); test_map = json.load(fp); fp.close(); print(json.dumps(test_map))') + else + keys=$(python3 -c 'keys = ["dummy"]; print(keys)') + test_map=$(python3 -c 'test_map = {"dummy": []}; print(test_map)') + fi + echo $keys + echo $test_map + echo "matrix=$keys" >> $GITHUB_OUTPUT + echo "test_map=$test_map" >> $GITHUB_OUTPUT + + run_pr_tests: + name: Run PR Tests + needs: setup_pr_tests + if: contains(fromJson(needs.setup_pr_tests.outputs.matrix), 'dummy') != true + strategy: + fail-fast: false + max-parallel: 2 + matrix: + modules: ${{ fromJson(needs.setup_pr_tests.outputs.matrix) }} + runs-on: + group: aws-general-8-plus + container: + image: diffusers/diffusers-pytorch-cpu + options: --shm-size "16gb" --ipc host -v /mnt/hf_cache:/mnt/cache/ + defaults: + run: + shell: bash + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m pip install -e [quality,test] + python -m pip install accelerate + + - name: Environment + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python utils/print_env.py + + - name: Run all selected tests on CPU + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m pytest -n 2 --dist=loadfile -v --make-reports=${{ matrix.modules }}_tests_cpu ${{ fromJson(needs.setup_pr_tests.outputs.test_map)[matrix.modules] }} + + - name: Failure short reports + if: ${{ failure() }} + continue-on-error: true + run: | + cat reports/${{ matrix.modules }}_tests_cpu_stats.txt + cat reports/${{ matrix.modules }}_tests_cpu_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v3 + with: + name: ${{ matrix.modules }}_test_reports + path: reports + + run_staging_tests: + strategy: + fail-fast: false + matrix: + config: + - name: Hub tests for models, schedulers, and pipelines + framework: hub_tests_pytorch + runner: aws-general-8-plus + image: diffusers/diffusers-pytorch-cpu + report: torch_hub + + name: ${{ matrix.config.name }} + runs-on: + group: ${{ matrix.config.runner }} + container: + image: ${{ matrix.config.image }} + options: --shm-size "16gb" --ipc host -v /mnt/hf_cache:/mnt/cache/ + + defaults: + run: + shell: bash + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m pip install -e [quality,test] + + - name: Environment + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python utils/print_env.py + + - name: Run Hub tests for models, schedulers, and pipelines on a staging env + if: ${{ matrix.config.framework == 'hub_tests_pytorch' }} + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + HUGGINGFACE_CO_STAGING=true python -m pytest \ + -m "is_staging_test" \ + --make-reports=tests_${{ matrix.config.report }} \ + tests + + - name: Failure short reports + if: ${{ failure() }} + run: cat reports/tests_${{ matrix.config.report }}_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: pr_${{ matrix.config.report }}_test_reports + path: reports diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_tests.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_tests.yml new file mode 100644 index 0000000000000000000000000000000000000000..dd55790626e68bc5ddbea4bc0b35470feebf746a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_tests.yml @@ -0,0 +1,303 @@ +name: Fast tests for PRs + +on: + pull_request: + branches: [main] + paths: + - "src/diffusers/**.py" + - "benchmarks/**.py" + - "examples/**.py" + - "scripts/**.py" + - "tests/**.py" + - ".github/**.yml" + - "utils/**.py" + - "setup.py" + push: + branches: + - ci-* + +concurrency: + group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }} + cancel-in-progress: true + +env: + DIFFUSERS_IS_CI: yes + HF_HUB_ENABLE_HF_TRANSFER: 1 + OMP_NUM_THREADS: 4 + MKL_NUM_THREADS: 4 + PYTEST_TIMEOUT: 60 + +jobs: + check_code_quality: + runs-on: ubuntu-22.04 + steps: + - uses: actions/checkout@v3 + - name: Set up Python + uses: actions/setup-python@v4 + with: + python-version: "3.8" + - name: Install dependencies + run: | + python -m pip install --upgrade pip + pip install .[quality] + - name: Check quality + run: make quality + - name: Check if failure + if: ${{ failure() }} + run: | + echo "Quality check failed. Please ensure the right dependency versions are installed with 'pip install -e .[quality]' and run 'make style && make quality'" >> $GITHUB_STEP_SUMMARY + + check_repository_consistency: + needs: check_code_quality + runs-on: ubuntu-22.04 + steps: + - uses: actions/checkout@v3 + - name: Set up Python + uses: actions/setup-python@v4 + with: + python-version: "3.8" + - name: Install dependencies + run: | + python -m pip install --upgrade pip + pip install .[quality] + - name: Check repo consistency + run: | + python utils/check_copies.py + python utils/check_dummies.py + python utils/check_support_list.py + make deps_table_check_updated + - name: Check if failure + if: ${{ failure() }} + run: | + echo "Repo consistency check failed. Please ensure the right dependency versions are installed with 'pip install -e .[quality]' and run 'make fix-copies'" >> $GITHUB_STEP_SUMMARY + + run_fast_tests: + needs: [check_code_quality, check_repository_consistency] + strategy: + fail-fast: false + matrix: + config: + - name: Fast PyTorch Pipeline CPU tests + framework: pytorch_pipelines + runner: aws-highmemory-32-plus + image: diffusers/diffusers-pytorch-cpu + report: torch_cpu_pipelines + - name: Fast PyTorch Models & Schedulers CPU tests + framework: pytorch_models + runner: aws-general-8-plus + image: diffusers/diffusers-pytorch-cpu + report: torch_cpu_models_schedulers + - name: Fast Flax CPU tests + framework: flax + runner: aws-general-8-plus + image: diffusers/diffusers-flax-cpu + report: flax_cpu + - name: PyTorch Example CPU tests + framework: pytorch_examples + runner: aws-general-8-plus + image: diffusers/diffusers-pytorch-cpu + report: torch_example_cpu + + name: ${{ matrix.config.name }} + + runs-on: + group: ${{ matrix.config.runner }} + + container: + image: ${{ matrix.config.image }} + options: --shm-size "16gb" --ipc host -v /mnt/hf_cache:/mnt/cache/ + + defaults: + run: + shell: bash + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + pip uninstall transformers -y && python -m uv pip install -U transformers@git+https://github.com/huggingface/transformers.git --no-deps + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git --no-deps + + - name: Environment + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python utils/print_env.py + + - name: Run fast PyTorch Pipeline CPU tests + if: ${{ matrix.config.framework == 'pytorch_pipelines' }} + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m pytest -n 8 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "not Flax and not Onnx" \ + --make-reports=tests_${{ matrix.config.report }} \ + tests/pipelines + + - name: Run fast PyTorch Model Scheduler CPU tests + if: ${{ matrix.config.framework == 'pytorch_models' }} + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m pytest -n 4 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "not Flax and not Onnx and not Dependency" \ + --make-reports=tests_${{ matrix.config.report }} \ + tests/models tests/schedulers tests/others + + - name: Run fast Flax TPU tests + if: ${{ matrix.config.framework == 'flax' }} + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m pytest -n 4 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "Flax" \ + --make-reports=tests_${{ matrix.config.report }} \ + tests + + - name: Run example PyTorch CPU tests + if: ${{ matrix.config.framework == 'pytorch_examples' }} + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install peft timm + python -m pytest -n 4 --max-worker-restart=0 --dist=loadfile \ + --make-reports=tests_${{ matrix.config.report }} \ + examples + + - name: Failure short reports + if: ${{ failure() }} + run: cat reports/tests_${{ matrix.config.report }}_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: pr_${{ matrix.config.framework }}_${{ matrix.config.report }}_test_reports + path: reports + + run_staging_tests: + needs: [check_code_quality, check_repository_consistency] + strategy: + fail-fast: false + matrix: + config: + - name: Hub tests for models, schedulers, and pipelines + framework: hub_tests_pytorch + runner: + group: aws-general-8-plus + image: diffusers/diffusers-pytorch-cpu + report: torch_hub + + name: ${{ matrix.config.name }} + + runs-on: ${{ matrix.config.runner }} + + container: + image: ${{ matrix.config.image }} + options: --shm-size "16gb" --ipc host -v /mnt/hf_cache:/mnt/cache/ + + defaults: + run: + shell: bash + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + + - name: Environment + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python utils/print_env.py + + - name: Run Hub tests for models, schedulers, and pipelines on a staging env + if: ${{ matrix.config.framework == 'hub_tests_pytorch' }} + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + HUGGINGFACE_CO_STAGING=true python -m pytest \ + -m "is_staging_test" \ + --make-reports=tests_${{ matrix.config.report }} \ + tests + + - name: Failure short reports + if: ${{ failure() }} + run: cat reports/tests_${{ matrix.config.report }}_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: pr_${{ matrix.config.report }}_test_reports + path: reports + + run_lora_tests: + needs: [check_code_quality, check_repository_consistency] + strategy: + fail-fast: false + + name: LoRA tests with PEFT main + + runs-on: + group: aws-general-8-plus + + container: + image: diffusers/diffusers-pytorch-cpu + options: --shm-size "16gb" --ipc host -v /mnt/hf_cache:/mnt/cache/ + + defaults: + run: + shell: bash + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + # TODO (sayakpaul, DN6): revisit `--no-deps` + python -m pip install -U peft@git+https://github.com/huggingface/peft.git --no-deps + python -m uv pip install -U transformers@git+https://github.com/huggingface/transformers.git --no-deps + python -m uv pip install -U tokenizers + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git --no-deps + + - name: Environment + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python utils/print_env.py + + - name: Run fast PyTorch LoRA tests with PEFT + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m pytest -n 4 --max-worker-restart=0 --dist=loadfile \ + -s -v \ + --make-reports=tests_peft_main \ + tests/lora/ + python -m pytest -n 4 --max-worker-restart=0 --dist=loadfile \ + -s -v \ + --make-reports=tests_models_lora_peft_main \ + tests/models/ -k "lora" + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_lora_failures_short.txt + cat reports/tests_models_lora_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: pr_main_test_reports + path: reports + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_tests_gpu.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_tests_gpu.yml new file mode 100644 index 0000000000000000000000000000000000000000..87d51773888ec3564b86d9b4859fd3193990c04d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_tests_gpu.yml @@ -0,0 +1,296 @@ +name: Fast GPU Tests on PR + +on: + pull_request: + branches: main + paths: + - "src/diffusers/models/modeling_utils.py" + - "src/diffusers/models/model_loading_utils.py" + - "src/diffusers/pipelines/pipeline_utils.py" + - "src/diffusers/pipeline_loading_utils.py" + - "src/diffusers/loaders/lora_base.py" + - "src/diffusers/loaders/lora_pipeline.py" + - "src/diffusers/loaders/peft.py" + - "tests/pipelines/test_pipelines_common.py" + - "tests/models/test_modeling_common.py" + workflow_dispatch: + +concurrency: + group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }} + cancel-in-progress: true + +env: + DIFFUSERS_IS_CI: yes + OMP_NUM_THREADS: 8 + MKL_NUM_THREADS: 8 + HF_HUB_ENABLE_HF_TRANSFER: 1 + PYTEST_TIMEOUT: 600 + PIPELINE_USAGE_CUTOFF: 1000000000 # set high cutoff so that only always-test pipelines run + +jobs: + check_code_quality: + runs-on: ubuntu-22.04 + steps: + - uses: actions/checkout@v3 + - name: Set up Python + uses: actions/setup-python@v4 + with: + python-version: "3.8" + - name: Install dependencies + run: | + python -m pip install --upgrade pip + pip install .[quality] + - name: Check quality + run: make quality + - name: Check if failure + if: ${{ failure() }} + run: | + echo "Quality check failed. Please ensure the right dependency versions are installed with 'pip install -e .[quality]' and run 'make style && make quality'" >> $GITHUB_STEP_SUMMARY + + check_repository_consistency: + needs: check_code_quality + runs-on: ubuntu-22.04 + steps: + - uses: actions/checkout@v3 + - name: Set up Python + uses: actions/setup-python@v4 + with: + python-version: "3.8" + - name: Install dependencies + run: | + python -m pip install --upgrade pip + pip install .[quality] + - name: Check repo consistency + run: | + python utils/check_copies.py + python utils/check_dummies.py + python utils/check_support_list.py + make deps_table_check_updated + - name: Check if failure + if: ${{ failure() }} + run: | + echo "Repo consistency check failed. Please ensure the right dependency versions are installed with 'pip install -e .[quality]' and run 'make fix-copies'" >> $GITHUB_STEP_SUMMARY + + setup_torch_cuda_pipeline_matrix: + needs: [check_code_quality, check_repository_consistency] + name: Setup Torch Pipelines CUDA Slow Tests Matrix + runs-on: + group: aws-general-8-plus + container: + image: diffusers/diffusers-pytorch-cpu + outputs: + pipeline_test_matrix: ${{ steps.fetch_pipeline_matrix.outputs.pipeline_test_matrix }} + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + - name: Environment + run: | + python utils/print_env.py + - name: Fetch Pipeline Matrix + id: fetch_pipeline_matrix + run: | + matrix=$(python utils/fetch_torch_cuda_pipeline_test_matrix.py) + echo $matrix + echo "pipeline_test_matrix=$matrix" >> $GITHUB_OUTPUT + - name: Pipeline Tests Artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: test-pipelines.json + path: reports + + torch_pipelines_cuda_tests: + name: Torch Pipelines CUDA Tests + needs: setup_torch_cuda_pipeline_matrix + strategy: + fail-fast: false + max-parallel: 8 + matrix: + module: ${{ fromJson(needs.setup_torch_cuda_pipeline_matrix.outputs.pipeline_test_matrix) }} + runs-on: + group: aws-g4dn-2xlarge + container: + image: diffusers/diffusers-pytorch-cuda + options: --shm-size "16gb" --ipc host --gpus 0 + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: NVIDIA-SMI + run: | + nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + pip uninstall transformers -y && python -m uv pip install -U transformers@git+https://github.com/huggingface/transformers.git --no-deps + + - name: Environment + run: | + python utils/print_env.py + - name: Extract tests + id: extract_tests + run: | + pattern=$(python utils/extract_tests_from_mixin.py --type pipeline) + echo "$pattern" > /tmp/test_pattern.txt + echo "pattern_file=/tmp/test_pattern.txt" >> $GITHUB_OUTPUT + + - name: PyTorch CUDA checkpoint tests on Ubuntu + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + run: | + if [ "${{ matrix.module }}" = "ip_adapters" ]; then + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "not Flax and not Onnx" \ + --make-reports=tests_pipeline_${{ matrix.module }}_cuda \ + tests/pipelines/${{ matrix.module }} + else + pattern=$(cat ${{ steps.extract_tests.outputs.pattern_file }}) + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "not Flax and not Onnx and $pattern" \ + --make-reports=tests_pipeline_${{ matrix.module }}_cuda \ + tests/pipelines/${{ matrix.module }} + fi + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_pipeline_${{ matrix.module }}_cuda_stats.txt + cat reports/tests_pipeline_${{ matrix.module }}_cuda_failures_short.txt + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: pipeline_${{ matrix.module }}_test_reports + path: reports + + torch_cuda_tests: + name: Torch CUDA Tests + needs: [check_code_quality, check_repository_consistency] + runs-on: + group: aws-g4dn-2xlarge + container: + image: diffusers/diffusers-pytorch-cuda + options: --shm-size "16gb" --ipc host --gpus 0 + defaults: + run: + shell: bash + strategy: + fail-fast: false + max-parallel: 2 + matrix: + module: [models, schedulers, lora, others] + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + python -m uv pip install peft@git+https://github.com/huggingface/peft.git + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + pip uninstall transformers -y && python -m uv pip install -U transformers@git+https://github.com/huggingface/transformers.git --no-deps + + - name: Environment + run: | + python utils/print_env.py + + - name: Extract tests + id: extract_tests + run: | + pattern=$(python utils/extract_tests_from_mixin.py --type ${{ matrix.module }}) + echo "$pattern" > /tmp/test_pattern.txt + echo "pattern_file=/tmp/test_pattern.txt" >> $GITHUB_OUTPUT + + - name: Run PyTorch CUDA tests + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + run: | + pattern=$(cat ${{ steps.extract_tests.outputs.pattern_file }}) + if [ -z "$pattern" ]; then + python -m pytest -n 1 -sv --max-worker-restart=0 --dist=loadfile -k "not Flax and not Onnx" tests/${{ matrix.module }} \ + --make-reports=tests_torch_cuda_${{ matrix.module }} + else + python -m pytest -n 1 -sv --max-worker-restart=0 --dist=loadfile -k "not Flax and not Onnx and $pattern" tests/${{ matrix.module }} \ + --make-reports=tests_torch_cuda_${{ matrix.module }} + fi + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_torch_cuda_${{ matrix.module }}_stats.txt + cat reports/tests_torch_cuda_${{ matrix.module }}_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_cuda_test_reports_${{ matrix.module }} + path: reports + + run_examples_tests: + name: Examples PyTorch CUDA tests on Ubuntu + needs: [check_code_quality, check_repository_consistency] + runs-on: + group: aws-g4dn-2xlarge + + container: + image: diffusers/diffusers-pytorch-cuda + options: --gpus 0 --shm-size "16gb" --ipc host + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: NVIDIA-SMI + run: | + nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + pip uninstall transformers -y && python -m uv pip install -U transformers@git+https://github.com/huggingface/transformers.git --no-deps + python -m uv pip install -e [quality,test,training] + + - name: Environment + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python utils/print_env.py + + - name: Run example tests on GPU + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install timm + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile -s -v --make-reports=examples_torch_cuda examples/ + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/examples_torch_cuda_stats.txt + cat reports/examples_torch_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: examples_test_reports + path: reports + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_torch_dependency_test.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_torch_dependency_test.yml new file mode 100644 index 0000000000000000000000000000000000000000..c39d5eca2d9a60214f348b1ca7ecfd90638e4470 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pr_torch_dependency_test.yml @@ -0,0 +1,36 @@ +name: Run Torch dependency tests + +on: + pull_request: + branches: + - main + paths: + - "src/diffusers/**.py" + push: + branches: + - main + +concurrency: + group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }} + cancel-in-progress: true + +jobs: + check_torch_dependencies: + runs-on: ubuntu-22.04 + steps: + - uses: actions/checkout@v3 + - name: Set up Python + uses: actions/setup-python@v4 + with: + python-version: "3.8" + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m pip install --upgrade pip uv + python -m uv pip install -e . + python -m uv pip install torch torchvision torchaudio + python -m uv pip install pytest + - name: Check for soft dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + pytest tests/others/test_dependencies.py diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/push_tests.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/push_tests.yml new file mode 100644 index 0000000000000000000000000000000000000000..7cab08b44fcd6af3de769bc5cb57354180ad6115 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/push_tests.yml @@ -0,0 +1,390 @@ +name: Fast GPU Tests on main + +on: + workflow_dispatch: + push: + branches: + - main + paths: + - "src/diffusers/**.py" + - "examples/**.py" + - "tests/**.py" + +env: + DIFFUSERS_IS_CI: yes + OMP_NUM_THREADS: 8 + MKL_NUM_THREADS: 8 + HF_HUB_ENABLE_HF_TRANSFER: 1 + PYTEST_TIMEOUT: 600 + PIPELINE_USAGE_CUTOFF: 50000 + +jobs: + setup_torch_cuda_pipeline_matrix: + name: Setup Torch Pipelines CUDA Slow Tests Matrix + runs-on: + group: aws-general-8-plus + container: + image: diffusers/diffusers-pytorch-cpu + outputs: + pipeline_test_matrix: ${{ steps.fetch_pipeline_matrix.outputs.pipeline_test_matrix }} + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + - name: Environment + run: | + python utils/print_env.py + - name: Fetch Pipeline Matrix + id: fetch_pipeline_matrix + run: | + matrix=$(python utils/fetch_torch_cuda_pipeline_test_matrix.py) + echo $matrix + echo "pipeline_test_matrix=$matrix" >> $GITHUB_OUTPUT + - name: Pipeline Tests Artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: test-pipelines.json + path: reports + + torch_pipelines_cuda_tests: + name: Torch Pipelines CUDA Tests + needs: setup_torch_cuda_pipeline_matrix + strategy: + fail-fast: false + max-parallel: 8 + matrix: + module: ${{ fromJson(needs.setup_torch_cuda_pipeline_matrix.outputs.pipeline_test_matrix) }} + runs-on: + group: aws-g4dn-2xlarge + container: + image: diffusers/diffusers-pytorch-cuda + options: --shm-size "16gb" --ipc host --gpus 0 + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + - name: NVIDIA-SMI + run: | + nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + - name: Environment + run: | + python utils/print_env.py + - name: PyTorch CUDA checkpoint tests on Ubuntu + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "not Flax and not Onnx" \ + --make-reports=tests_pipeline_${{ matrix.module }}_cuda \ + tests/pipelines/${{ matrix.module }} + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_pipeline_${{ matrix.module }}_cuda_stats.txt + cat reports/tests_pipeline_${{ matrix.module }}_cuda_failures_short.txt + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: pipeline_${{ matrix.module }}_test_reports + path: reports + + torch_cuda_tests: + name: Torch CUDA Tests + runs-on: + group: aws-g4dn-2xlarge + container: + image: diffusers/diffusers-pytorch-cuda + options: --shm-size "16gb" --ipc host --gpus 0 + defaults: + run: + shell: bash + strategy: + fail-fast: false + max-parallel: 2 + matrix: + module: [models, schedulers, lora, others, single_file] + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + python -m uv pip install peft@git+https://github.com/huggingface/peft.git + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + + - name: Environment + run: | + python utils/print_env.py + + - name: Run PyTorch CUDA tests + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "not Flax and not Onnx" \ + --make-reports=tests_torch_cuda_${{ matrix.module }} \ + tests/${{ matrix.module }} + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_torch_cuda_${{ matrix.module }}_stats.txt + cat reports/tests_torch_cuda_${{ matrix.module }}_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_cuda_test_reports_${{ matrix.module }} + path: reports + + flax_tpu_tests: + name: Flax TPU Tests + runs-on: + group: gcp-ct5lp-hightpu-8t + container: + image: diffusers/diffusers-flax-tpu + options: --shm-size "16gb" --ipc host --privileged ${{ vars.V5_LITEPOD_8_ENV}} -v /mnt/hf_cache:/mnt/hf_cache + defaults: + run: + shell: bash + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + + - name: Environment + run: | + python utils/print_env.py + + - name: Run Flax TPU tests + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + run: | + python -m pytest -n 0 \ + -s -v -k "Flax" \ + --make-reports=tests_flax_tpu \ + tests/ + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_flax_tpu_stats.txt + cat reports/tests_flax_tpu_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: flax_tpu_test_reports + path: reports + + onnx_cuda_tests: + name: ONNX CUDA Tests + runs-on: + group: aws-g4dn-2xlarge + container: + image: diffusers/diffusers-onnxruntime-cuda + options: --shm-size "16gb" --ipc host -v /mnt/cache/.cache/huggingface:/mnt/cache/ --gpus 0 + defaults: + run: + shell: bash + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + + - name: Environment + run: | + python utils/print_env.py + + - name: Run ONNXRuntime CUDA tests + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "Onnx" \ + --make-reports=tests_onnx_cuda \ + tests/ + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_onnx_cuda_stats.txt + cat reports/tests_onnx_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: onnx_cuda_test_reports + path: reports + + run_torch_compile_tests: + name: PyTorch Compile CUDA tests + + runs-on: + group: aws-g4dn-2xlarge + + container: + image: diffusers/diffusers-pytorch-cuda + options: --gpus 0 --shm-size "16gb" --ipc host + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: NVIDIA-SMI + run: | + nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test,training] + - name: Environment + run: | + python utils/print_env.py + - name: Run example tests on GPU + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + RUN_COMPILE: yes + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile -s -v -k "compile" --make-reports=tests_torch_compile_cuda tests/ + - name: Failure short reports + if: ${{ failure() }} + run: cat reports/tests_torch_compile_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_compile_test_reports + path: reports + + run_xformers_tests: + name: PyTorch xformers CUDA tests + + runs-on: + group: aws-g4dn-2xlarge + + container: + image: diffusers/diffusers-pytorch-xformers-cuda + options: --gpus 0 --shm-size "16gb" --ipc host + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: NVIDIA-SMI + run: | + nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test,training] + - name: Environment + run: | + python utils/print_env.py + - name: Run example tests on GPU + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile -s -v -k "xformers" --make-reports=tests_torch_xformers_cuda tests/ + - name: Failure short reports + if: ${{ failure() }} + run: cat reports/tests_torch_xformers_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_xformers_test_reports + path: reports + + run_examples_tests: + name: Examples PyTorch CUDA tests on Ubuntu + + runs-on: + group: aws-g4dn-2xlarge + + container: + image: diffusers/diffusers-pytorch-cuda + options: --gpus 0 --shm-size "16gb" --ipc host + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: NVIDIA-SMI + run: | + nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test,training] + + - name: Environment + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python utils/print_env.py + + - name: Run example tests on GPU + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install timm + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile -s -v --make-reports=examples_torch_cuda examples/ + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/examples_torch_cuda_stats.txt + cat reports/examples_torch_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: examples_test_reports + path: reports diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/push_tests_fast.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/push_tests_fast.yml new file mode 100644 index 0000000000000000000000000000000000000000..e8a73446de737999a05b7d3e829e5a4832425bce --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/push_tests_fast.yml @@ -0,0 +1,126 @@ +name: Fast tests on main + +on: + push: + branches: + - main + paths: + - "src/diffusers/**.py" + - "examples/**.py" + - "tests/**.py" + +concurrency: + group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }} + cancel-in-progress: true + +env: + DIFFUSERS_IS_CI: yes + HF_HOME: /mnt/cache + OMP_NUM_THREADS: 8 + MKL_NUM_THREADS: 8 + HF_HUB_ENABLE_HF_TRANSFER: 1 + PYTEST_TIMEOUT: 600 + RUN_SLOW: no + +jobs: + run_fast_tests: + strategy: + fail-fast: false + matrix: + config: + - name: Fast PyTorch CPU tests on Ubuntu + framework: pytorch + runner: aws-general-8-plus + image: diffusers/diffusers-pytorch-cpu + report: torch_cpu + - name: Fast Flax CPU tests on Ubuntu + framework: flax + runner: aws-general-8-plus + image: diffusers/diffusers-flax-cpu + report: flax_cpu + - name: Fast ONNXRuntime CPU tests on Ubuntu + framework: onnxruntime + runner: aws-general-8-plus + image: diffusers/diffusers-onnxruntime-cpu + report: onnx_cpu + - name: PyTorch Example CPU tests on Ubuntu + framework: pytorch_examples + runner: aws-general-8-plus + image: diffusers/diffusers-pytorch-cpu + report: torch_example_cpu + + name: ${{ matrix.config.name }} + + runs-on: + group: ${{ matrix.config.runner }} + + container: + image: ${{ matrix.config.image }} + options: --shm-size "16gb" --ipc host -v /mnt/hf_cache:/mnt/cache/ + + defaults: + run: + shell: bash + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + + - name: Environment + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python utils/print_env.py + + - name: Run fast PyTorch CPU tests + if: ${{ matrix.config.framework == 'pytorch' }} + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m pytest -n 4 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "not Flax and not Onnx" \ + --make-reports=tests_${{ matrix.config.report }} \ + tests/ + + - name: Run fast Flax TPU tests + if: ${{ matrix.config.framework == 'flax' }} + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m pytest -n 4 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "Flax" \ + --make-reports=tests_${{ matrix.config.report }} \ + tests/ + + - name: Run fast ONNXRuntime CPU tests + if: ${{ matrix.config.framework == 'onnxruntime' }} + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m pytest -n 4 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "Onnx" \ + --make-reports=tests_${{ matrix.config.report }} \ + tests/ + + - name: Run example PyTorch CPU tests + if: ${{ matrix.config.framework == 'pytorch_examples' }} + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install peft timm + python -m pytest -n 4 --max-worker-restart=0 --dist=loadfile \ + --make-reports=tests_${{ matrix.config.report }} \ + examples + + - name: Failure short reports + if: ${{ failure() }} + run: cat reports/tests_${{ matrix.config.report }}_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: pr_${{ matrix.config.report }}_test_reports + path: reports diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/push_tests_mps.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/push_tests_mps.yml new file mode 100644 index 0000000000000000000000000000000000000000..5fd3b78be7df6a6e159013365a4d0493598d3afe --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/push_tests_mps.yml @@ -0,0 +1,76 @@ +name: Fast mps tests on main + +on: + push: + branches: + - main + paths: + - "src/diffusers/**.py" + - "tests/**.py" + +env: + DIFFUSERS_IS_CI: yes + HF_HOME: /mnt/cache + OMP_NUM_THREADS: 8 + MKL_NUM_THREADS: 8 + HF_HUB_ENABLE_HF_TRANSFER: 1 + PYTEST_TIMEOUT: 600 + RUN_SLOW: no + +concurrency: + group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }} + cancel-in-progress: true + +jobs: + run_fast_tests_apple_m1: + name: Fast PyTorch MPS tests on MacOS + runs-on: macos-13-xlarge + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Clean checkout + shell: arch -arch arm64 bash {0} + run: | + git clean -fxd + + - name: Setup miniconda + uses: ./.github/actions/setup-miniconda + with: + python-version: 3.9 + + - name: Install dependencies + shell: arch -arch arm64 bash {0} + run: | + ${CONDA_RUN} python -m pip install --upgrade pip uv + ${CONDA_RUN} python -m uv pip install -e ".[quality,test]" + ${CONDA_RUN} python -m uv pip install torch torchvision torchaudio + ${CONDA_RUN} python -m uv pip install accelerate@git+https://github.com/huggingface/accelerate.git + ${CONDA_RUN} python -m uv pip install transformers --upgrade + + - name: Environment + shell: arch -arch arm64 bash {0} + run: | + ${CONDA_RUN} python utils/print_env.py + + - name: Run fast PyTorch tests on M1 (MPS) + shell: arch -arch arm64 bash {0} + env: + HF_HOME: /System/Volumes/Data/mnt/cache + HF_TOKEN: ${{ secrets.HF_TOKEN }} + run: | + ${CONDA_RUN} python -m pytest -n 0 -s -v --make-reports=tests_torch_mps tests/ + + - name: Failure short reports + if: ${{ failure() }} + run: cat reports/tests_torch_mps_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: pr_torch_mps_test_reports + path: reports diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pypi_publish.yaml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pypi_publish.yaml new file mode 100644 index 0000000000000000000000000000000000000000..dc36b6b024c57f29de77e0ef22a148e4bc269dd6 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/pypi_publish.yaml @@ -0,0 +1,81 @@ +# Adapted from https://blog.deepjyoti30.dev/pypi-release-github-action + +name: PyPI release + +on: + workflow_dispatch: + push: + tags: + - "*" + +jobs: + find-and-checkout-latest-branch: + runs-on: ubuntu-22.04 + outputs: + latest_branch: ${{ steps.set_latest_branch.outputs.latest_branch }} + steps: + - name: Checkout Repo + uses: actions/checkout@v3 + + - name: Set up Python + uses: actions/setup-python@v4 + with: + python-version: '3.8' + + - name: Fetch latest branch + id: fetch_latest_branch + run: | + pip install -U requests packaging + LATEST_BRANCH=$(python utils/fetch_latest_release_branch.py) + echo "Latest branch: $LATEST_BRANCH" + echo "latest_branch=$LATEST_BRANCH" >> $GITHUB_ENV + + - name: Set latest branch output + id: set_latest_branch + run: echo "::set-output name=latest_branch::${{ env.latest_branch }}" + + release: + needs: find-and-checkout-latest-branch + runs-on: ubuntu-22.04 + + steps: + - name: Checkout Repo + uses: actions/checkout@v3 + with: + ref: ${{ needs.find-and-checkout-latest-branch.outputs.latest_branch }} + + - name: Setup Python + uses: actions/setup-python@v4 + with: + python-version: "3.8" + + - name: Install dependencies + run: | + python -m pip install --upgrade pip + pip install -U setuptools wheel twine + pip install -U torch --index-url https://download.pytorch.org/whl/cpu + pip install -U transformers + + - name: Build the dist files + run: python setup.py bdist_wheel && python setup.py sdist + + - name: Publish to the test PyPI + env: + TWINE_USERNAME: ${{ secrets.TEST_PYPI_USERNAME }} + TWINE_PASSWORD: ${{ secrets.TEST_PYPI_PASSWORD }} + run: twine upload dist/* -r pypitest --repository-url=https://test.pypi.org/legacy/ + + - name: Test installing diffusers and importing + run: | + pip install diffusers && pip uninstall diffusers -y + pip install -i https://test.pypi.org/simple/ diffusers + python -c "from diffusers import __version__; print(__version__)" + python -c "from diffusers import DiffusionPipeline; pipe = DiffusionPipeline.from_pretrained('fusing/unet-ldm-dummy-update'); pipe()" + python -c "from diffusers import DiffusionPipeline; pipe = DiffusionPipeline.from_pretrained('hf-internal-testing/tiny-stable-diffusion-pipe', safety_checker=None); pipe('ah suh du')" + python -c "from diffusers import *" + + - name: Publish to PyPI + env: + TWINE_USERNAME: ${{ secrets.PYPI_USERNAME }} + TWINE_PASSWORD: ${{ secrets.PYPI_PASSWORD }} + run: twine upload dist/* -r pypi diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/release_tests_fast.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/release_tests_fast.yml new file mode 100644 index 0000000000000000000000000000000000000000..a464381ba48a950f19c63bc105457311dedf9f07 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/release_tests_fast.yml @@ -0,0 +1,446 @@ +# Duplicate workflow to push_tests.yml that is meant to run on release/patch branches as a final check +# Creating a duplicate workflow here is simpler than adding complex path/branch parsing logic to push_tests.yml +# Needs to be updated if push_tests.yml updated +name: (Release) Fast GPU Tests on main + +on: + push: + branches: + - "v*.*.*-release" + - "v*.*.*-patch" + +env: + DIFFUSERS_IS_CI: yes + OMP_NUM_THREADS: 8 + MKL_NUM_THREADS: 8 + PYTEST_TIMEOUT: 600 + PIPELINE_USAGE_CUTOFF: 50000 + +jobs: + setup_torch_cuda_pipeline_matrix: + name: Setup Torch Pipelines CUDA Slow Tests Matrix + runs-on: + group: aws-general-8-plus + container: + image: diffusers/diffusers-pytorch-cpu + outputs: + pipeline_test_matrix: ${{ steps.fetch_pipeline_matrix.outputs.pipeline_test_matrix }} + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + - name: Environment + run: | + python utils/print_env.py + - name: Fetch Pipeline Matrix + id: fetch_pipeline_matrix + run: | + matrix=$(python utils/fetch_torch_cuda_pipeline_test_matrix.py) + echo $matrix + echo "pipeline_test_matrix=$matrix" >> $GITHUB_OUTPUT + - name: Pipeline Tests Artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: test-pipelines.json + path: reports + + torch_pipelines_cuda_tests: + name: Torch Pipelines CUDA Tests + needs: setup_torch_cuda_pipeline_matrix + strategy: + fail-fast: false + max-parallel: 8 + matrix: + module: ${{ fromJson(needs.setup_torch_cuda_pipeline_matrix.outputs.pipeline_test_matrix) }} + runs-on: + group: aws-g4dn-2xlarge + container: + image: diffusers/diffusers-pytorch-cuda + options: --shm-size "16gb" --ipc host --gpus 0 + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + - name: NVIDIA-SMI + run: | + nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + - name: Environment + run: | + python utils/print_env.py + - name: Slow PyTorch CUDA checkpoint tests on Ubuntu + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "not Flax and not Onnx" \ + --make-reports=tests_pipeline_${{ matrix.module }}_cuda \ + tests/pipelines/${{ matrix.module }} + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_pipeline_${{ matrix.module }}_cuda_stats.txt + cat reports/tests_pipeline_${{ matrix.module }}_cuda_failures_short.txt + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: pipeline_${{ matrix.module }}_test_reports + path: reports + + torch_cuda_tests: + name: Torch CUDA Tests + runs-on: + group: aws-g4dn-2xlarge + container: + image: diffusers/diffusers-pytorch-cuda + options: --shm-size "16gb" --ipc host --gpus 0 + defaults: + run: + shell: bash + strategy: + fail-fast: false + max-parallel: 2 + matrix: + module: [models, schedulers, lora, others, single_file] + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + python -m uv pip install peft@git+https://github.com/huggingface/peft.git + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + + - name: Environment + run: | + python utils/print_env.py + + - name: Run PyTorch CUDA tests + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "not Flax and not Onnx" \ + --make-reports=tests_torch_${{ matrix.module }}_cuda \ + tests/${{ matrix.module }} + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_torch_${{ matrix.module }}_cuda_stats.txt + cat reports/tests_torch_${{ matrix.module }}_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_cuda_${{ matrix.module }}_test_reports + path: reports + + torch_minimum_version_cuda_tests: + name: Torch Minimum Version CUDA Tests + runs-on: + group: aws-g4dn-2xlarge + container: + image: diffusers/diffusers-pytorch-minimum-cuda + options: --shm-size "16gb" --ipc host --gpus 0 + defaults: + run: + shell: bash + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + python -m uv pip install peft@git+https://github.com/huggingface/peft.git + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + + - name: Environment + run: | + python utils/print_env.py + + - name: Run PyTorch CUDA tests + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + # https://pytorch.org/docs/stable/notes/randomness.html#avoiding-nondeterministic-algorithms + CUBLAS_WORKSPACE_CONFIG: :16:8 + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "not Flax and not Onnx" \ + --make-reports=tests_torch_minimum_cuda \ + tests/models/test_modeling_common.py \ + tests/pipelines/test_pipelines_common.py \ + tests/pipelines/test_pipeline_utils.py \ + tests/pipelines/test_pipelines.py \ + tests/pipelines/test_pipelines_auto.py \ + tests/schedulers/test_schedulers.py \ + tests/others + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_torch_minimum_version_cuda_stats.txt + cat reports/tests_torch_minimum_version_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_minimum_version_cuda_test_reports + path: reports + + flax_tpu_tests: + name: Flax TPU Tests + runs-on: docker-tpu + container: + image: diffusers/diffusers-flax-tpu + options: --shm-size "16gb" --ipc host -v /mnt/cache/.cache/huggingface:/mnt/cache/ --privileged + defaults: + run: + shell: bash + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + + - name: Environment + run: | + python utils/print_env.py + + - name: Run slow Flax TPU tests + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + run: | + python -m pytest -n 0 \ + -s -v -k "Flax" \ + --make-reports=tests_flax_tpu \ + tests/ + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_flax_tpu_stats.txt + cat reports/tests_flax_tpu_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: flax_tpu_test_reports + path: reports + + onnx_cuda_tests: + name: ONNX CUDA Tests + runs-on: + group: aws-g4dn-2xlarge + container: + image: diffusers/diffusers-onnxruntime-cuda + options: --shm-size "16gb" --ipc host -v /mnt/cache/.cache/huggingface:/mnt/cache/ --gpus 0 + defaults: + run: + shell: bash + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + pip uninstall accelerate -y && python -m uv pip install -U accelerate@git+https://github.com/huggingface/accelerate.git + + - name: Environment + run: | + python utils/print_env.py + + - name: Run slow ONNXRuntime CUDA tests + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile \ + -s -v -k "Onnx" \ + --make-reports=tests_onnx_cuda \ + tests/ + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/tests_onnx_cuda_stats.txt + cat reports/tests_onnx_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: onnx_cuda_test_reports + path: reports + + run_torch_compile_tests: + name: PyTorch Compile CUDA tests + + runs-on: + group: aws-g4dn-2xlarge + + container: + image: diffusers/diffusers-pytorch-cuda + options: --gpus 0 --shm-size "16gb" --ipc host + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: NVIDIA-SMI + run: | + nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test,training] + - name: Environment + run: | + python utils/print_env.py + - name: Run torch compile tests on GPU + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + RUN_COMPILE: yes + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile -s -v -k "compile" --make-reports=tests_torch_compile_cuda tests/ + - name: Failure short reports + if: ${{ failure() }} + run: cat reports/tests_torch_compile_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_compile_test_reports + path: reports + + run_xformers_tests: + name: PyTorch xformers CUDA tests + + runs-on: + group: aws-g4dn-2xlarge + + container: + image: diffusers/diffusers-pytorch-xformers-cuda + options: --gpus 0 --shm-size "16gb" --ipc host + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: NVIDIA-SMI + run: | + nvidia-smi + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test,training] + - name: Environment + run: | + python utils/print_env.py + - name: Run example tests on GPU + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + run: | + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile -s -v -k "xformers" --make-reports=tests_torch_xformers_cuda tests/ + - name: Failure short reports + if: ${{ failure() }} + run: cat reports/tests_torch_xformers_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: torch_xformers_test_reports + path: reports + + run_examples_tests: + name: Examples PyTorch CUDA tests on Ubuntu + + runs-on: + group: aws-g4dn-2xlarge + + container: + image: diffusers/diffusers-pytorch-cuda + options: --gpus 0 --shm-size "16gb" --ipc host + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: NVIDIA-SMI + run: | + nvidia-smi + + - name: Install dependencies + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test,training] + + - name: Environment + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python utils/print_env.py + + - name: Run example tests on GPU + env: + HF_TOKEN: ${{ secrets.DIFFUSERS_HF_HUB_READ_TOKEN }} + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install timm + python -m pytest -n 1 --max-worker-restart=0 --dist=loadfile -s -v --make-reports=examples_torch_cuda examples/ + + - name: Failure short reports + if: ${{ failure() }} + run: | + cat reports/examples_torch_cuda_stats.txt + cat reports/examples_torch_cuda_failures_short.txt + + - name: Test suite reports artifacts + if: ${{ always() }} + uses: actions/upload-artifact@v4 + with: + name: examples_test_reports + path: reports diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/run_tests_from_a_pr.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/run_tests_from_a_pr.yml new file mode 100644 index 0000000000000000000000000000000000000000..94fbb2d297c51107b4b790d1304a05cc10aa6e77 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/run_tests_from_a_pr.yml @@ -0,0 +1,74 @@ +name: Check running SLOW tests from a PR (only GPU) + +on: + workflow_dispatch: + inputs: + docker_image: + default: 'diffusers/diffusers-pytorch-cuda' + description: 'Name of the Docker image' + required: true + pr_number: + description: 'PR number to test on' + required: true + test: + description: 'Tests to run (e.g.: `tests/models`).' + required: true + +env: + DIFFUSERS_IS_CI: yes + IS_GITHUB_CI: "1" + HF_HOME: /mnt/cache + OMP_NUM_THREADS: 8 + MKL_NUM_THREADS: 8 + PYTEST_TIMEOUT: 600 + RUN_SLOW: yes + +jobs: + run_tests: + name: "Run a test on our runner from a PR" + runs-on: + group: aws-g4dn-2xlarge + container: + image: ${{ github.event.inputs.docker_image }} + options: --gpus 0 --privileged --ipc host -v /mnt/cache/.cache/huggingface:/mnt/cache/ + + steps: + - name: Validate test files input + id: validate_test_files + env: + PY_TEST: ${{ github.event.inputs.test }} + run: | + if [[ ! "$PY_TEST" =~ ^tests/ ]]; then + echo "Error: The input string must start with 'tests/'." + exit 1 + fi + + if [[ ! "$PY_TEST" =~ ^tests/(models|pipelines|lora) ]]; then + echo "Error: The input string must contain either 'models', 'pipelines', or 'lora' after 'tests/'." + exit 1 + fi + + if [[ "$PY_TEST" == *";"* ]]; then + echo "Error: The input string must not contain ';'." + exit 1 + fi + echo "$PY_TEST" + + shell: bash -e {0} + + - name: Checkout PR branch + uses: actions/checkout@v4 + with: + ref: refs/pull/${{ inputs.pr_number }}/head + + - name: Install pytest + run: | + python -m venv /opt/venv && export PATH="/opt/venv/bin:$PATH" + python -m uv pip install -e [quality,test] + python -m uv pip install peft + + - name: Run tests + env: + PY_TEST: ${{ github.event.inputs.test }} + run: | + pytest "$PY_TEST" diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/ssh-pr-runner.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/ssh-pr-runner.yml new file mode 100644 index 0000000000000000000000000000000000000000..49fa9c0ad24d65634a891496ac93bc93e9e24378 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/ssh-pr-runner.yml @@ -0,0 +1,40 @@ +name: SSH into PR runners + +on: + workflow_dispatch: + inputs: + docker_image: + description: 'Name of the Docker image' + required: true + +env: + IS_GITHUB_CI: "1" + HF_HUB_READ_TOKEN: ${{ secrets.HF_HUB_READ_TOKEN }} + HF_HOME: /mnt/cache + DIFFUSERS_IS_CI: yes + OMP_NUM_THREADS: 8 + MKL_NUM_THREADS: 8 + RUN_SLOW: yes + +jobs: + ssh_runner: + name: "SSH" + runs-on: + group: aws-highmemory-32-plus + container: + image: ${{ github.event.inputs.docker_image }} + options: --shm-size "16gb" --ipc host -v /mnt/cache/.cache/huggingface/diffusers:/mnt/cache/ --privileged + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: Tailscale # In order to be able to SSH when a test fails + uses: huggingface/tailscale-action@main + with: + authkey: ${{ secrets.TAILSCALE_SSH_AUTHKEY }} + slackChannel: ${{ secrets.SLACK_CIFEEDBACK_CHANNEL }} + slackToken: ${{ secrets.SLACK_CIFEEDBACK_BOT_TOKEN }} + waitForSSH: true diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/ssh-runner.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/ssh-runner.yml new file mode 100644 index 0000000000000000000000000000000000000000..fd65598a53a78de498589547ad75c14518b2d0cc --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/ssh-runner.yml @@ -0,0 +1,52 @@ +name: SSH into GPU runners + +on: + workflow_dispatch: + inputs: + runner_type: + description: 'Type of runner to test (aws-g6-4xlarge-plus: a10, aws-g4dn-2xlarge: t4, aws-g6e-xlarge-plus: L40)' + type: choice + required: true + options: + - aws-g6-4xlarge-plus + - aws-g4dn-2xlarge + - aws-g6e-xlarge-plus + docker_image: + description: 'Name of the Docker image' + required: true + +env: + IS_GITHUB_CI: "1" + HF_HUB_READ_TOKEN: ${{ secrets.HF_HUB_READ_TOKEN }} + HF_HOME: /mnt/cache + DIFFUSERS_IS_CI: yes + OMP_NUM_THREADS: 8 + MKL_NUM_THREADS: 8 + RUN_SLOW: yes + +jobs: + ssh_runner: + name: "SSH" + runs-on: + group: "${{ github.event.inputs.runner_type }}" + container: + image: ${{ github.event.inputs.docker_image }} + options: --shm-size "16gb" --ipc host -v /mnt/cache/.cache/huggingface/diffusers:/mnt/cache/ --gpus 0 --privileged + + steps: + - name: Checkout diffusers + uses: actions/checkout@v3 + with: + fetch-depth: 2 + + - name: NVIDIA-SMI + run: | + nvidia-smi + + - name: Tailscale # In order to be able to SSH when a test fails + uses: huggingface/tailscale-action@main + with: + authkey: ${{ secrets.TAILSCALE_SSH_AUTHKEY }} + slackChannel: ${{ secrets.SLACK_CIFEEDBACK_CHANNEL }} + slackToken: ${{ secrets.SLACK_CIFEEDBACK_BOT_TOKEN }} + waitForSSH: true diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/stale.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/stale.yml new file mode 100644 index 0000000000000000000000000000000000000000..27450ed4c7f20d4534b4c4597ca019267e12dd81 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/stale.yml @@ -0,0 +1,30 @@ +name: Stale Bot + +on: + schedule: + - cron: "0 15 * * *" + +jobs: + close_stale_issues: + name: Close Stale Issues + if: github.repository == 'huggingface/diffusers' + runs-on: ubuntu-22.04 + permissions: + issues: write + pull-requests: write + env: + GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }} + steps: + - uses: actions/checkout@v2 + + - name: Setup Python + uses: actions/setup-python@v1 + with: + python-version: 3.8 + + - name: Install requirements + run: | + pip install PyGithub + - name: Close stale issues + run: | + python utils/stale.py diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/trufflehog.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/trufflehog.yml new file mode 100644 index 0000000000000000000000000000000000000000..4743dc35245533652c81a3c1ac0d5fb1bca92bc1 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/trufflehog.yml @@ -0,0 +1,18 @@ +on: + push: + +name: Secret Leaks + +jobs: + trufflehog: + runs-on: ubuntu-22.04 + steps: + - name: Checkout code + uses: actions/checkout@v4 + with: + fetch-depth: 0 + - name: Secret Scanning + uses: trufflesecurity/trufflehog@main + with: + extra_args: --results=verified,unknown + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/typos.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/typos.yml new file mode 100644 index 0000000000000000000000000000000000000000..6d2f2fc8dd9a69a626bd9852e2add65cb32dfdc9 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/typos.yml @@ -0,0 +1,14 @@ +name: Check typos + +on: + workflow_dispatch: + +jobs: + build: + runs-on: ubuntu-22.04 + + steps: + - uses: actions/checkout@v3 + + - name: typos-action + uses: crate-ci/typos@v1.12.4 diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/update_metadata.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/update_metadata.yml new file mode 100644 index 0000000000000000000000000000000000000000..92aea0369ba855237b39d4dee9e8daee0c81010d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/update_metadata.yml @@ -0,0 +1,30 @@ +name: Update Diffusers metadata + +on: + workflow_dispatch: + push: + branches: + - main + - update_diffusers_metadata* + +jobs: + update_metadata: + runs-on: ubuntu-22.04 + defaults: + run: + shell: bash -l {0} + + steps: + - uses: actions/checkout@v3 + + - name: Setup environment + run: | + pip install --upgrade pip + pip install datasets pandas + pip install .[torch] + + - name: Update metadata + env: + HF_TOKEN: ${{ secrets.SAYAK_HF_TOKEN }} + run: | + python utils/update_metadata.py --commit_sha ${{ github.sha }} diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/upload_pr_documentation.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/upload_pr_documentation.yml new file mode 100644 index 0000000000000000000000000000000000000000..fc102df8103e48fb139a8bd47be05fc257d992c5 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.github/workflows/upload_pr_documentation.yml @@ -0,0 +1,16 @@ +name: Upload PR Documentation + +on: + workflow_run: + workflows: ["Build PR Documentation"] + types: + - completed + +jobs: + build: + uses: huggingface/doc-builder/.github/workflows/upload_pr_documentation.yml@main + with: + package_name: diffusers + secrets: + hf_token: ${{ secrets.HF_DOC_BUILD_PUSH }} + comment_bot_token: ${{ secrets.COMMENT_BOT_TOKEN }} diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/.gitignore b/tasks/tasksmith-48efdcc71e7d/tests/source/.gitignore new file mode 100644 index 0000000000000000000000000000000000000000..15617d5fdc745f57271db05b5fe7fd83f440c3a7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/.gitignore @@ -0,0 +1,178 @@ +# Initially taken from GitHub's Python gitignore file + +# Byte-compiled / optimized / DLL files +__pycache__/ +*.py[cod] +*$py.class + +# C extensions +*.so + +# tests and logs +tests/fixtures/cached_*_text.txt +logs/ +lightning_logs/ +lang_code_data/ + +# Distribution / packaging +.Python +build/ +develop-eggs/ +dist/ +downloads/ +eggs/ +.eggs/ +lib/ +lib64/ +parts/ +sdist/ +var/ +wheels/ +*.egg-info/ +.installed.cfg +*.egg +MANIFEST + +# PyInstaller +# Usually these files are written by a Python script from a template +# before PyInstaller builds the exe, so as to inject date/other infos into it. +*.manifest +*.spec + +# Installer logs +pip-log.txt +pip-delete-this-directory.txt + +# Unit test / coverage reports +htmlcov/ +.tox/ +.nox/ +.coverage +.coverage.* +.cache +nosetests.xml +coverage.xml +*.cover +.hypothesis/ +.pytest_cache/ + +# Translations +*.mo +*.pot + +# Django stuff: +*.log +local_settings.py +db.sqlite3 + +# Flask stuff: +instance/ +.webassets-cache + +# Scrapy stuff: +.scrapy + +# Sphinx documentation +docs/_build/ + +# PyBuilder +target/ + +# Jupyter Notebook +.ipynb_checkpoints + +# IPython +profile_default/ +ipython_config.py + +# pyenv +.python-version + +# celery beat schedule file +celerybeat-schedule + +# SageMath parsed files +*.sage.py + +# Environments +.env +.venv +env/ +venv/ +ENV/ +env.bak/ +venv.bak/ + +# Spyder project settings +.spyderproject +.spyproject + +# Rope project settings +.ropeproject + +# mkdocs documentation +/site + +# mypy +.mypy_cache/ +.dmypy.json +dmypy.json + +# Pyre type checker +.pyre/ + +# vscode +.vs +.vscode + +# Pycharm +.idea + +# TF code +tensorflow_code + +# Models +proc_data + +# examples +runs +/runs_old +/wandb +/examples/runs +/examples/**/*.args +/examples/rag/sweep + +# data +/data +serialization_dir + +# emacs +*.*~ +debug.env + +# vim +.*.swp + +# ctags +tags + +# pre-commit +.pre-commit* + +# .lock +*.lock + +# DS_Store (MacOS) +.DS_Store + +# RL pipelines may produce mp4 outputs +*.mp4 + +# dependencies +/transformers + +# ruff +.ruff_cache + +# wandb +wandb \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/CITATION.cff b/tasks/tasksmith-48efdcc71e7d/tests/source/CITATION.cff new file mode 100644 index 0000000000000000000000000000000000000000..09fc6c744d06407fa6b4707af1afe3cc9529b4db --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/CITATION.cff @@ -0,0 +1,52 @@ +cff-version: 1.2.0 +title: 'Diffusers: State-of-the-art diffusion models' +message: >- + If you use this software, please cite it using the + metadata from this file. +type: software +authors: + - given-names: Patrick + family-names: von Platen + - given-names: Suraj + family-names: Patil + - given-names: Anton + family-names: Lozhkov + - given-names: Pedro + family-names: Cuenca + - given-names: Nathan + family-names: Lambert + - given-names: Kashif + family-names: Rasul + - given-names: Mishig + family-names: Davaadorj + - given-names: Dhruv + family-names: Nair + - given-names: Sayak + family-names: Paul + - given-names: Steven + family-names: Liu + - given-names: William + family-names: Berman + - given-names: Yiyi + family-names: Xu + - given-names: Thomas + family-names: Wolf +repository-code: 'https://github.com/huggingface/diffusers' +abstract: >- + Diffusers provides pretrained diffusion models across + multiple modalities, such as vision and audio, and serves + as a modular toolbox for inference and training of + diffusion models. +keywords: + - deep-learning + - pytorch + - image-generation + - hacktoberfest + - diffusion + - text2image + - image2image + - score-based-generative-modeling + - stable-diffusion + - stable-diffusion-diffusers +license: Apache-2.0 +version: 0.12.1 diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/CODE_OF_CONDUCT.md b/tasks/tasksmith-48efdcc71e7d/tests/source/CODE_OF_CONDUCT.md new file mode 100644 index 0000000000000000000000000000000000000000..2139079964fbd53692380985e60ef90e2fa05dad --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/CODE_OF_CONDUCT.md @@ -0,0 +1,130 @@ + +# Contributor Covenant Code of Conduct + +## Our Pledge + +We as members, contributors, and leaders pledge to make participation in our +community a harassment-free experience for everyone, regardless of age, body +size, visible or invisible disability, ethnicity, sex characteristics, gender +identity and expression, level of experience, education, socio-economic status, +nationality, personal appearance, race, caste, color, religion, or sexual identity +and orientation. + +We pledge to act and interact in ways that contribute to an open, welcoming, +diverse, inclusive, and healthy community. + +## Our Standards + +Examples of behavior that contributes to a positive environment for our +community include: + +* Demonstrating empathy and kindness toward other people +* Being respectful of differing opinions, viewpoints, and experiences +* Giving and gracefully accepting constructive feedback +* Accepting responsibility and apologizing to those affected by our mistakes, + and learning from the experience +* Focusing on what is best not just for us as individuals, but for the + overall Diffusers community + +Examples of unacceptable behavior include: + +* The use of sexualized language or imagery, and sexual attention or + advances of any kind +* Trolling, insulting or derogatory comments, and personal or political attacks +* Public or private harassment +* Publishing others' private information, such as a physical or email + address, without their explicit permission +* Spamming issues or PRs with links to projects unrelated to this library +* Other conduct which could reasonably be considered inappropriate in a + professional setting + +## Enforcement Responsibilities + +Community leaders are responsible for clarifying and enforcing our standards of +acceptable behavior and will take appropriate and fair corrective action in +response to any behavior that they deem inappropriate, threatening, offensive, +or harmful. + +Community leaders have the right and responsibility to remove, edit, or reject +comments, commits, code, wiki edits, issues, and other contributions that are +not aligned to this Code of Conduct, and will communicate reasons for moderation +decisions when appropriate. + +## Scope + +This Code of Conduct applies within all community spaces, and also applies when +an individual is officially representing the community in public spaces. +Examples of representing our community include using an official e-mail address, +posting via an official social media account, or acting as an appointed +representative at an online or offline event. + +## Enforcement + +Instances of abusive, harassing, or otherwise unacceptable behavior may be +reported to the community leaders responsible for enforcement at +feedback@huggingface.co. +All complaints will be reviewed and investigated promptly and fairly. + +All community leaders are obligated to respect the privacy and security of the +reporter of any incident. + +## Enforcement Guidelines + +Community leaders will follow these Community Impact Guidelines in determining +the consequences for any action they deem in violation of this Code of Conduct: + +### 1. Correction + +**Community Impact**: Use of inappropriate language or other behavior deemed +unprofessional or unwelcome in the community. + +**Consequence**: A private, written warning from community leaders, providing +clarity around the nature of the violation and an explanation of why the +behavior was inappropriate. A public apology may be requested. + +### 2. Warning + +**Community Impact**: A violation through a single incident or series +of actions. + +**Consequence**: A warning with consequences for continued behavior. No +interaction with the people involved, including unsolicited interaction with +those enforcing the Code of Conduct, for a specified period of time. This +includes avoiding interactions in community spaces as well as external channels +like social media. Violating these terms may lead to a temporary or +permanent ban. + +### 3. Temporary Ban + +**Community Impact**: A serious violation of community standards, including +sustained inappropriate behavior. + +**Consequence**: A temporary ban from any sort of interaction or public +communication with the community for a specified period of time. No public or +private interaction with the people involved, including unsolicited interaction +with those enforcing the Code of Conduct, is allowed during this period. +Violating these terms may lead to a permanent ban. + +### 4. Permanent Ban + +**Community Impact**: Demonstrating a pattern of violation of community +standards, including sustained inappropriate behavior, harassment of an +individual, or aggression toward or disparagement of classes of individuals. + +**Consequence**: A permanent ban from any sort of public interaction within +the community. + +## Attribution + +This Code of Conduct is adapted from the [Contributor Covenant][homepage], +version 2.1, available at +https://www.contributor-covenant.org/version/2/1/code_of_conduct.html. + +Community Impact Guidelines were inspired by [Mozilla's code of conduct +enforcement ladder](https://github.com/mozilla/diversity). + +[homepage]: https://www.contributor-covenant.org + +For answers to common questions about this code of conduct, see the FAQ at +https://www.contributor-covenant.org/faq. Translations are available at +https://www.contributor-covenant.org/translations. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/CONTRIBUTING.md b/tasks/tasksmith-48efdcc71e7d/tests/source/CONTRIBUTING.md new file mode 100644 index 0000000000000000000000000000000000000000..049d317599ad2292504acf3d139b332bc64cbe74 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/CONTRIBUTING.md @@ -0,0 +1,506 @@ + + +# How to contribute to Diffusers 🧨 + +We ❤️ contributions from the open-source community! Everyone is welcome, and all types of participation –not just code– are valued and appreciated. Answering questions, helping others, reaching out, and improving the documentation are all immensely valuable to the community, so don't be afraid and get involved if you're up for it! + +Everyone is encouraged to start by saying 👋 in our public Discord channel. We discuss the latest trends in diffusion models, ask questions, show off personal projects, help each other with contributions, or just hang out ☕. Join us on Discord + +Whichever way you choose to contribute, we strive to be part of an open, welcoming, and kind community. Please, read our [code of conduct](https://github.com/huggingface/diffusers/blob/main/CODE_OF_CONDUCT.md) and be mindful to respect it during your interactions. We also recommend you become familiar with the [ethical guidelines](https://huggingface.co/docs/diffusers/conceptual/ethical_guidelines) that guide our project and ask you to adhere to the same principles of transparency and responsibility. + +We enormously value feedback from the community, so please do not be afraid to speak up if you believe you have valuable feedback that can help improve the library - every message, comment, issue, and pull request (PR) is read and considered. + +## Overview + +You can contribute in many ways ranging from answering questions on issues to adding new diffusion models to +the core library. + +In the following, we give an overview of different ways to contribute, ranked by difficulty in ascending order. All of them are valuable to the community. + +* 1. Asking and answering questions on [the Diffusers discussion forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers) or on [Discord](https://discord.gg/G7tWnz98XR). +* 2. Opening new issues on [the GitHub Issues tab](https://github.com/huggingface/diffusers/issues/new/choose). +* 3. Answering issues on [the GitHub Issues tab](https://github.com/huggingface/diffusers/issues). +* 4. Fix a simple issue, marked by the "Good first issue" label, see [here](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22). +* 5. Contribute to the [documentation](https://github.com/huggingface/diffusers/tree/main/docs/source). +* 6. Contribute a [Community Pipeline](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3Acommunity-examples). +* 7. Contribute to the [examples](https://github.com/huggingface/diffusers/tree/main/examples). +* 8. Fix a more difficult issue, marked by the "Good second issue" label, see [here](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22Good+second+issue%22). +* 9. Add a new pipeline, model, or scheduler, see ["New Pipeline/Model"](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+pipeline%2Fmodel%22) and ["New scheduler"](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+scheduler%22) issues. For this contribution, please have a look at [Design Philosophy](https://github.com/huggingface/diffusers/blob/main/PHILOSOPHY.md). + +As said before, **all contributions are valuable to the community**. +In the following, we will explain each contribution a bit more in detail. + +For all contributions 4-9, you will need to open a PR. It is explained in detail how to do so in [Opening a pull request](#how-to-open-a-pr). + +### 1. Asking and answering questions on the Diffusers discussion forum or on the Diffusers Discord + +Any question or comment related to the Diffusers library can be asked on the [discussion forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/) or on [Discord](https://discord.gg/G7tWnz98XR). Such questions and comments include (but are not limited to): +- Reports of training or inference experiments in an attempt to share knowledge +- Presentation of personal projects +- Questions to non-official training examples +- Project proposals +- General feedback +- Paper summaries +- Asking for help on personal projects that build on top of the Diffusers library +- General questions +- Ethical questions regarding diffusion models +- ... + +Every question that is asked on the forum or on Discord actively encourages the community to publicly +share knowledge and might very well help a beginner in the future who has the same question you're +having. Please do pose any questions you might have. +In the same spirit, you are of immense help to the community by answering such questions because this way you are publicly documenting knowledge for everybody to learn from. + +**Please** keep in mind that the more effort you put into asking or answering a question, the higher +the quality of the publicly documented knowledge. In the same way, well-posed and well-answered questions create a high-quality knowledge database accessible to everybody, while badly posed questions or answers reduce the overall quality of the public knowledge database. +In short, a high quality question or answer is *precise*, *concise*, *relevant*, *easy-to-understand*, *accessible*, and *well-formatted/well-posed*. For more information, please have a look through the [How to write a good issue](#how-to-write-a-good-issue) section. + +**NOTE about channels**: +[*The forum*](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) is much better indexed by search engines, such as Google. Posts are ranked by popularity rather than chronologically. Hence, it's easier to look up questions and answers that we posted some time ago. +In addition, questions and answers posted in the forum can easily be linked to. +In contrast, *Discord* has a chat-like format that invites fast back-and-forth communication. +While it will most likely take less time for you to get an answer to your question on Discord, your +question won't be visible anymore over time. Also, it's much harder to find information that was posted a while back on Discord. We therefore strongly recommend using the forum for high-quality questions and answers in an attempt to create long-lasting knowledge for the community. If discussions on Discord lead to very interesting answers and conclusions, we recommend posting the results on the forum to make the information more available for future readers. + +### 2. Opening new issues on the GitHub issues tab + +The 🧨 Diffusers library is robust and reliable thanks to the users who notify us of +the problems they encounter. So thank you for reporting an issue. + +Remember, GitHub issues are reserved for technical questions directly related to the Diffusers library, bug reports, feature requests, or feedback on the library design. + +In a nutshell, this means that everything that is **not** related to the **code of the Diffusers library** (including the documentation) should **not** be asked on GitHub, but rather on either the [forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) or [Discord](https://discord.gg/G7tWnz98XR). + +**Please consider the following guidelines when opening a new issue**: +- Make sure you have searched whether your issue has already been asked before (use the search bar on GitHub under Issues). +- Please never report a new issue on another (related) issue. If another issue is highly related, please +open a new issue nevertheless and link to the related issue. +- Make sure your issue is written in English. Please use one of the great, free online translation services, such as [DeepL](https://www.deepl.com/translator) to translate from your native language to English if you are not comfortable in English. +- Check whether your issue might be solved by updating to the newest Diffusers version. Before posting your issue, please make sure that `python -c "import diffusers; print(diffusers.__version__)"` is higher or matches the latest Diffusers version. +- Remember that the more effort you put into opening a new issue, the higher the quality of your answer will be and the better the overall quality of the Diffusers issues. + +New issues usually include the following. + +#### 2.1. Reproducible, minimal bug reports + +A bug report should always have a reproducible code snippet and be as minimal and concise as possible. +This means in more detail: +- Narrow the bug down as much as you can, **do not just dump your whole code file**. +- Format your code. +- Do not include any external libraries except for Diffusers depending on them. +- **Always** provide all necessary information about your environment; for this, you can run: `diffusers-cli env` in your shell and copy-paste the displayed information to the issue. +- Explain the issue. If the reader doesn't know what the issue is and why it is an issue, she cannot solve it. +- **Always** make sure the reader can reproduce your issue with as little effort as possible. If your code snippet cannot be run because of missing libraries or undefined variables, the reader cannot help you. Make sure your reproducible code snippet is as minimal as possible and can be copy-pasted into a simple Python shell. +- If in order to reproduce your issue a model and/or dataset is required, make sure the reader has access to that model or dataset. You can always upload your model or dataset to the [Hub](https://huggingface.co) to make it easily downloadable. Try to keep your model and dataset as small as possible, to make the reproduction of your issue as effortless as possible. + +For more information, please have a look through the [How to write a good issue](#how-to-write-a-good-issue) section. + +You can open a bug report [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=bug&projects=&template=bug-report.yml). + +#### 2.2. Feature requests + +A world-class feature request addresses the following points: + +1. Motivation first: +* Is it related to a problem/frustration with the library? If so, please explain +why. Providing a code snippet that demonstrates the problem is best. +* Is it related to something you would need for a project? We'd love to hear +about it! +* Is it something you worked on and think could benefit the community? +Awesome! Tell us what problem it solved for you. +2. Write a *full paragraph* describing the feature; +3. Provide a **code snippet** that demonstrates its future use; +4. In case this is related to a paper, please attach a link; +5. Attach any additional information (drawings, screenshots, etc.) you think may help. + +You can open a feature request [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feature_request.md&title=). + +#### 2.3 Feedback + +Feedback about the library design and why it is good or not good helps the core maintainers immensely to build a user-friendly library. To understand the philosophy behind the current design philosophy, please have a look [here](https://huggingface.co/docs/diffusers/conceptual/philosophy). If you feel like a certain design choice does not fit with the current design philosophy, please explain why and how it should be changed. If a certain design choice follows the design philosophy too much, hence restricting use cases, explain why and how it should be changed. +If a certain design choice is very useful for you, please also leave a note as this is great feedback for future design decisions. + +You can open an issue about feedback [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feedback.md&title=). + +#### 2.4 Technical questions + +Technical questions are mainly about why certain code of the library was written in a certain way, or what a certain part of the code does. Please make sure to link to the code in question and please provide detail on +why this part of the code is difficult to understand. + +You can open an issue about a technical question [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=bug&template=bug-report.yml). + +#### 2.5 Proposal to add a new model, scheduler, or pipeline + +If the diffusion model community released a new model, pipeline, or scheduler that you would like to see in the Diffusers library, please provide the following information: + +* Short description of the diffusion pipeline, model, or scheduler and link to the paper or public release. +* Link to any of its open-source implementation. +* Link to the model weights if they are available. + +If you are willing to contribute to the model yourself, let us know so we can best guide you. Also, don't forget +to tag the original author of the component (model, scheduler, pipeline, etc.) by GitHub handle if you can find it. + +You can open a request for a model/pipeline/scheduler [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=New+model%2Fpipeline%2Fscheduler&template=new-model-addition.yml). + +### 3. Answering issues on the GitHub issues tab + +Answering issues on GitHub might require some technical knowledge of Diffusers, but we encourage everybody to give it a try even if you are not 100% certain that your answer is correct. +Some tips to give a high-quality answer to an issue: +- Be as concise and minimal as possible. +- Stay on topic. An answer to the issue should concern the issue and only the issue. +- Provide links to code, papers, or other sources that prove or encourage your point. +- Answer in code. If a simple code snippet is the answer to the issue or shows how the issue can be solved, please provide a fully reproducible code snippet. + +Also, many issues tend to be simply off-topic, duplicates of other issues, or irrelevant. It is of great +help to the maintainers if you can answer such issues, encouraging the author of the issue to be +more precise, provide the link to a duplicated issue or redirect them to [the forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) or [Discord](https://discord.gg/G7tWnz98XR). + +If you have verified that the issued bug report is correct and requires a correction in the source code, +please have a look at the next sections. + +For all of the following contributions, you will need to open a PR. It is explained in detail how to do so in the [Opening a pull request](#how-to-open-a-pr) section. + +### 4. Fixing a "Good first issue" + +*Good first issues* are marked by the [Good first issue](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22) label. Usually, the issue already +explains how a potential solution should look so that it is easier to fix. +If the issue hasn't been closed and you would like to try to fix this issue, you can just leave a message "I would like to try this issue.". There are usually three scenarios: +- a.) The issue description already proposes a fix. In this case and if the solution makes sense to you, you can open a PR or draft PR to fix it. +- b.) The issue description does not propose a fix. In this case, you can ask what a proposed fix could look like and someone from the Diffusers team should answer shortly. If you have a good idea of how to fix it, feel free to directly open a PR. +- c.) There is already an open PR to fix the issue, but the issue hasn't been closed yet. If the PR has gone stale, you can simply open a new PR and link to the stale PR. PRs often go stale if the original contributor who wanted to fix the issue suddenly cannot find the time anymore to proceed. This often happens in open-source and is very normal. In this case, the community will be very happy if you give it a new try and leverage the knowledge of the existing PR. If there is already a PR and it is active, you can help the author by giving suggestions, reviewing the PR or even asking whether you can contribute to the PR. + + +### 5. Contribute to the documentation + +A good library **always** has good documentation! The official documentation is often one of the first points of contact for new users of the library, and therefore contributing to the documentation is a **highly +valuable contribution**. + +Contributing to the library can have many forms: + +- Correcting spelling or grammatical errors. +- Correct incorrect formatting of the docstring. If you see that the official documentation is weirdly displayed or a link is broken, we are very happy if you take some time to correct it. +- Correct the shape or dimensions of a docstring input or output tensor. +- Clarify documentation that is hard to understand or incorrect. +- Update outdated code examples. +- Translating the documentation to another language. + +Anything displayed on [the official Diffusers doc page](https://huggingface.co/docs/diffusers/index) is part of the official documentation and can be corrected, adjusted in the respective [documentation source](https://github.com/huggingface/diffusers/tree/main/docs/source). + +Please have a look at [this page](https://github.com/huggingface/diffusers/tree/main/docs) on how to verify changes made to the documentation locally. + + +### 6. Contribute a community pipeline + +[Pipelines](https://huggingface.co/docs/diffusers/api/pipelines/overview) are usually the first point of contact between the Diffusers library and the user. +Pipelines are examples of how to use Diffusers [models](https://huggingface.co/docs/diffusers/api/models/overview) and [schedulers](https://huggingface.co/docs/diffusers/api/schedulers/overview). +We support two types of pipelines: + +- Official Pipelines +- Community Pipelines + +Both official and community pipelines follow the same design and consist of the same type of components. + +Official pipelines are tested and maintained by the core maintainers of Diffusers. Their code +resides in [src/diffusers/pipelines](https://github.com/huggingface/diffusers/tree/main/src/diffusers/pipelines). +In contrast, community pipelines are contributed and maintained purely by the **community** and are **not** tested. +They reside in [examples/community](https://github.com/huggingface/diffusers/tree/main/examples/community) and while they can be accessed via the [PyPI diffusers package](https://pypi.org/project/diffusers/), their code is not part of the PyPI distribution. + +The reason for the distinction is that the core maintainers of the Diffusers library cannot maintain and test all +possible ways diffusion models can be used for inference, but some of them may be of interest to the community. +Officially released diffusion pipelines, +such as Stable Diffusion are added to the core src/diffusers/pipelines package which ensures +high quality of maintenance, no backward-breaking code changes, and testing. +More bleeding edge pipelines should be added as community pipelines. If usage for a community pipeline is high, the pipeline can be moved to the official pipelines upon request from the community. This is one of the ways we strive to be a community-driven library. + +To add a community pipeline, one should add a .py file to [examples/community](https://github.com/huggingface/diffusers/tree/main/examples/community) and adapt the [examples/community/README.md](https://github.com/huggingface/diffusers/tree/main/examples/community/README.md) to include an example of the new pipeline. + +An example can be seen [here](https://github.com/huggingface/diffusers/pull/2400). + +Community pipeline PRs are only checked at a superficial level and ideally they should be maintained by their original authors. + +Contributing a community pipeline is a great way to understand how Diffusers models and schedulers work. Having contributed a community pipeline is usually the first stepping stone to contributing an official pipeline to the +core package. + +### 7. Contribute to training examples + +Diffusers examples are a collection of training scripts that reside in [examples](https://github.com/huggingface/diffusers/tree/main/examples). + +We support two types of training examples: + +- Official training examples +- Research training examples + +Research training examples are located in [examples/research_projects](https://github.com/huggingface/diffusers/tree/main/examples/research_projects) whereas official training examples include all folders under [examples](https://github.com/huggingface/diffusers/tree/main/examples) except the `research_projects` and `community` folders. +The official training examples are maintained by the Diffusers' core maintainers whereas the research training examples are maintained by the community. +This is because of the same reasons put forward in [6. Contribute a community pipeline](#6-contribute-a-community-pipeline) for official pipelines vs. community pipelines: It is not feasible for the core maintainers to maintain all possible training methods for diffusion models. +If the Diffusers core maintainers and the community consider a certain training paradigm to be too experimental or not popular enough, the corresponding training code should be put in the `research_projects` folder and maintained by the author. + +Both official training and research examples consist of a directory that contains one or more training scripts, a `requirements.txt` file, and a `README.md` file. In order for the user to make use of the +training examples, it is required to clone the repository: + +```bash +git clone https://github.com/huggingface/diffusers +``` + +as well as to install all additional dependencies required for training: + +```bash +cd diffusers +pip install -r examples//requirements.txt +``` + +Therefore when adding an example, the `requirements.txt` file shall define all pip dependencies required for your training example so that once all those are installed, the user can run the example's training script. See, for example, the [DreamBooth `requirements.txt` file](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/requirements.txt). + +Training examples of the Diffusers library should adhere to the following philosophy: +- All the code necessary to run the examples should be found in a single Python file. +- One should be able to run the example from the command line with `python .py --args`. +- Examples should be kept simple and serve as **an example** on how to use Diffusers for training. The purpose of example scripts is **not** to create state-of-the-art diffusion models, but rather to reproduce known training schemes without adding too much custom logic. As a byproduct of this point, our examples also strive to serve as good educational materials. + +To contribute an example, it is highly recommended to look at already existing examples such as [dreambooth](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/train_dreambooth.py) to get an idea of how they should look like. +We strongly advise contributors to make use of the [Accelerate library](https://github.com/huggingface/accelerate) as it's tightly integrated +with Diffusers. +Once an example script works, please make sure to add a comprehensive `README.md` that states how to use the example exactly. This README should include: +- An example command on how to run the example script as shown [here e.g.](https://github.com/huggingface/diffusers/tree/main/examples/dreambooth#running-locally-with-pytorch). +- A link to some training results (logs, models, ...) that show what the user can expect as shown [here e.g.](https://api.wandb.ai/report/patrickvonplaten/xm6cd5q5). +- If you are adding a non-official/research training example, **please don't forget** to add a sentence that you are maintaining this training example which includes your git handle as shown [here](https://github.com/huggingface/diffusers/tree/main/examples/research_projects/intel_opts#diffusers-examples-with-intel-optimizations). + +If you are contributing to the official training examples, please also make sure to add a test to [examples/test_examples.py](https://github.com/huggingface/diffusers/blob/main/examples/test_examples.py). This is not necessary for non-official training examples. + +### 8. Fixing a "Good second issue" + +*Good second issues* are marked by the [Good second issue](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22Good+second+issue%22) label. Good second issues are +usually more complicated to solve than [Good first issues](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22). +The issue description usually gives less guidance on how to fix the issue and requires +a decent understanding of the library by the interested contributor. +If you are interested in tackling a good second issue, feel free to open a PR to fix it and link the PR to the issue. If you see that a PR has already been opened for this issue but did not get merged, have a look to understand why it wasn't merged and try to open an improved PR. +Good second issues are usually more difficult to get merged compared to good first issues, so don't hesitate to ask for help from the core maintainers. If your PR is almost finished the core maintainers can also jump into your PR and commit to it in order to get it merged. + +### 9. Adding pipelines, models, schedulers + +Pipelines, models, and schedulers are the most important pieces of the Diffusers library. +They provide easy access to state-of-the-art diffusion technologies and thus allow the community to +build powerful generative AI applications. + +By adding a new model, pipeline, or scheduler you might enable a new powerful use case for any of the user interfaces relying on Diffusers which can be of immense value for the whole generative AI ecosystem. + +Diffusers has a couple of open feature requests for all three components - feel free to gloss over them +if you don't know yet what specific component you would like to add: +- [Model or pipeline](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+pipeline%2Fmodel%22) +- [Scheduler](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+scheduler%22) + +Before adding any of the three components, it is strongly recommended that you give the [Philosophy guide](https://github.com/huggingface/diffusers/blob/main/PHILOSOPHY.md) a read to better understand the design of any of the three components. Please be aware that +we cannot merge model, scheduler, or pipeline additions that strongly diverge from our design philosophy +as it will lead to API inconsistencies. If you fundamentally disagree with a design choice, please +open a [Feedback issue](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feedback.md&title=) instead so that it can be discussed whether a certain design +pattern/design choice shall be changed everywhere in the library and whether we shall update our design philosophy. Consistency across the library is very important for us. + +Please make sure to add links to the original codebase/paper to the PR and ideally also ping the +original author directly on the PR so that they can follow the progress and potentially help with questions. + +If you are unsure or stuck in the PR, don't hesitate to leave a message to ask for a first review or help. + +## How to write a good issue + +**The better your issue is written, the higher the chances that it will be quickly resolved.** + +1. Make sure that you've used the correct template for your issue. You can pick between *Bug Report*, *Feature Request*, *Feedback about API Design*, *New model/pipeline/scheduler addition*, *Forum*, or a blank issue. Make sure to pick the correct one when opening [a new issue](https://github.com/huggingface/diffusers/issues/new/choose). +2. **Be precise**: Give your issue a fitting title. Try to formulate your issue description as simple as possible. The more precise you are when submitting an issue, the less time it takes to understand the issue and potentially solve it. Make sure to open an issue for one issue only and not for multiple issues. If you found multiple issues, simply open multiple issues. If your issue is a bug, try to be as precise as possible about what bug it is - you should not just write "Error in diffusers". +3. **Reproducibility**: No reproducible code snippet == no solution. If you encounter a bug, maintainers **have to be able to reproduce** it. Make sure that you include a code snippet that can be copy-pasted into a Python interpreter to reproduce the issue. Make sure that your code snippet works, *i.e.* that there are no missing imports or missing links to images, ... Your issue should contain an error message **and** a code snippet that can be copy-pasted without any changes to reproduce the exact same error message. If your issue is using local model weights or local data that cannot be accessed by the reader, the issue cannot be solved. If you cannot share your data or model, try to make a dummy model or dummy data. +4. **Minimalistic**: Try to help the reader as much as you can to understand the issue as quickly as possible by staying as concise as possible. Remove all code / all information that is irrelevant to the issue. If you have found a bug, try to create the easiest code example you can to demonstrate your issue, do not just dump your whole workflow into the issue as soon as you have found a bug. E.g., if you train a model and get an error at some point during the training, you should first try to understand what part of the training code is responsible for the error and try to reproduce it with a couple of lines. Try to use dummy data instead of full datasets. +5. Add links. If you are referring to a certain naming, method, or model make sure to provide a link so that the reader can better understand what you mean. If you are referring to a specific PR or issue, make sure to link it to your issue. Do not assume that the reader knows what you are talking about. The more links you add to your issue the better. +6. Formatting. Make sure to nicely format your issue by formatting code into Python code syntax, and error messages into normal code syntax. See the [official GitHub formatting docs](https://docs.github.com/en/get-started/writing-on-github/getting-started-with-writing-and-formatting-on-github/basic-writing-and-formatting-syntax) for more information. +7. Think of your issue not as a ticket to be solved, but rather as a beautiful entry to a well-written encyclopedia. Every added issue is a contribution to publicly available knowledge. By adding a nicely written issue you not only make it easier for maintainers to solve your issue, but you are helping the whole community to better understand a certain aspect of the library. + +## How to write a good PR + +1. Be a chameleon. Understand existing design patterns and syntax and make sure your code additions flow seamlessly into the existing code base. Pull requests that significantly diverge from existing design patterns or user interfaces will not be merged. +2. Be laser focused. A pull request should solve one problem and one problem only. Make sure to not fall into the trap of "also fixing another problem while we're adding it". It is much more difficult to review pull requests that solve multiple, unrelated problems at once. +3. If helpful, try to add a code snippet that displays an example of how your addition can be used. +4. The title of your pull request should be a summary of its contribution. +5. If your pull request addresses an issue, please mention the issue number in +the pull request description to make sure they are linked (and people +consulting the issue know you are working on it); +6. To indicate a work in progress please prefix the title with `[WIP]`. These +are useful to avoid duplicated work, and to differentiate it from PRs ready +to be merged; +7. Try to formulate and format your text as explained in [How to write a good issue](#how-to-write-a-good-issue). +8. Make sure existing tests pass; +9. Add high-coverage tests. No quality testing = no merge. +- If you are adding new `@slow` tests, make sure they pass using +`RUN_SLOW=1 python -m pytest tests/test_my_new_model.py`. +CircleCI does not run the slow tests, but GitHub Actions does every night! +10. All public methods must have informative docstrings that work nicely with markdown. See [`pipeline_latent_diffusion.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/latent_diffusion/pipeline_latent_diffusion.py) for an example. +11. Due to the rapidly growing repository, it is important to make sure that no files that would significantly weigh down the repository are added. This includes images, videos, and other non-text files. We prefer to leverage a hf.co hosted `dataset` like +[`hf-internal-testing`](https://huggingface.co/hf-internal-testing) or [huggingface/documentation-images](https://huggingface.co/datasets/huggingface/documentation-images) to place these files. +If an external contribution, feel free to add the images to your PR and ask a Hugging Face member to migrate your images +to this dataset. + +## How to open a PR + +Before writing code, we strongly advise you to search through the existing PRs or +issues to make sure that nobody is already working on the same thing. If you are +unsure, it is always a good idea to open an issue to get some feedback. + +You will need basic `git` proficiency to be able to contribute to +🧨 Diffusers. `git` is not the easiest tool to use but it has the greatest +manual. Type `git --help` in a shell and enjoy. If you prefer books, [Pro +Git](https://git-scm.com/book/en/v2) is a very good reference. + +Follow these steps to start contributing ([supported Python versions](https://github.com/huggingface/diffusers/blob/42f25d601a910dceadaee6c44345896b4cfa9928/setup.py#L270)): + +1. Fork the [repository](https://github.com/huggingface/diffusers) by +clicking on the 'Fork' button on the repository's page. This creates a copy of the code +under your GitHub user account. + +2. Clone your fork to your local disk, and add the base repository as a remote: + + ```bash + $ git clone git@github.com:/diffusers.git + $ cd diffusers + $ git remote add upstream https://github.com/huggingface/diffusers.git + ``` + +3. Create a new branch to hold your development changes: + + ```bash + $ git checkout -b a-descriptive-name-for-my-changes + ``` + +**Do not** work on the `main` branch. + +4. Set up a development environment by running the following command in a virtual environment: + + ```bash + $ pip install -e ".[dev]" + ``` + +If you have already cloned the repo, you might need to `git pull` to get the most recent changes in the +library. + +5. Develop the features on your branch. + +As you work on the features, you should make sure that the test suite +passes. You should run the tests impacted by your changes like this: + + ```bash + $ pytest tests/.py + ``` + +Before you run the tests, please make sure you install the dependencies required for testing. You can do so +with this command: + + ```bash + $ pip install -e ".[test]" + ``` + +You can also run the full test suite with the following command, but it takes +a beefy machine to produce a result in a decent amount of time now that +Diffusers has grown a lot. Here is the command for it: + + ```bash + $ make test + ``` + +🧨 Diffusers relies on `ruff` and `isort` to format its source code +consistently. After you make changes, apply automatic style corrections and code verifications +that can't be automated in one go with: + + ```bash + $ make style + ``` + +🧨 Diffusers also uses `ruff` and a few custom scripts to check for coding mistakes. Quality +control runs in CI, however, you can also run the same checks with: + + ```bash + $ make quality + ``` + +Once you're happy with your changes, add changed files using `git add` and +make a commit with `git commit` to record your changes locally: + + ```bash + $ git add modified_file.py + $ git commit -m "A descriptive message about your changes." + ``` + +It is a good idea to sync your copy of the code with the original +repository regularly. This way you can quickly account for changes: + + ```bash + $ git pull upstream main + ``` + +Push the changes to your account using: + + ```bash + $ git push -u origin a-descriptive-name-for-my-changes + ``` + +6. Once you are satisfied, go to the +webpage of your fork on GitHub. Click on 'Pull request' to send your changes +to the project maintainers for review. + +7. It's ok if maintainers ask you for changes. It happens to core contributors +too! So everyone can see the changes in the Pull request, work in your local +branch and push the changes to your fork. They will automatically appear in +the pull request. + +### Tests + +An extensive test suite is included to test the library behavior and several examples. Library tests can be found in +the [tests folder](https://github.com/huggingface/diffusers/tree/main/tests). + +We like `pytest` and `pytest-xdist` because it's faster. From the root of the +repository, here's how to run tests with `pytest` for the library: + +```bash +$ python -m pytest -n auto --dist=loadfile -s -v ./tests/ +``` + +In fact, that's how `make test` is implemented! + +You can specify a smaller set of tests in order to test only the feature +you're working on. + +By default, slow tests are skipped. Set the `RUN_SLOW` environment variable to +`yes` to run them. This will download many gigabytes of models — make sure you +have enough disk space and a good Internet connection, or a lot of patience! + +```bash +$ RUN_SLOW=yes python -m pytest -n auto --dist=loadfile -s -v ./tests/ +``` + +`unittest` is fully supported, here's how to run tests with it: + +```bash +$ python -m unittest discover -s tests -t . -v +$ python -m unittest discover -s examples -t examples -v +``` + +### Syncing forked main with upstream (HuggingFace) main + +To avoid pinging the upstream repository which adds reference notes to each upstream PR and sends unnecessary notifications to the developers involved in these PRs, +when syncing the main branch of a forked repository, please, follow these steps: +1. When possible, avoid syncing with the upstream using a branch and PR on the forked repository. Instead, merge directly into the forked main. +2. If a PR is absolutely necessary, use the following steps after checking out your branch: +```bash +$ git checkout -b your-branch-for-syncing +$ git pull --squash --no-commit upstream main +$ git commit -m '' +$ git push --set-upstream origin your-branch-for-syncing +``` + +### Style guide + +For documentation strings, 🧨 Diffusers follows the [Google style](https://google.github.io/styleguide/pyguide.html). diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/Dockerfile b/tasks/tasksmith-48efdcc71e7d/tests/source/Dockerfile new file mode 100644 index 0000000000000000000000000000000000000000..ad62b0b947d7cd828c375a683292c05608d69afe --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/Dockerfile @@ -0,0 +1,10 @@ +FROM python:3.12-slim +WORKDIR /workspace +RUN python -m pip install --no-cache-dir --extra-index-url https://download.pytorch.org/whl/cpu torch==2.11.0+cpu numpy==2.5.3 transformers==4.49.0 tokenizers==0.21.4 huggingface-hub==0.35.3 accelerate==1.4.0 safetensors==0.4.5 sentencepiece==0.2.0 protobuf==3.20.3 pillow==12.3.0 parameterized==0.9.0 pytest==8.4.2 pytest-timeout==2.3.1 packaging==26.3 setuptools==78.1.0 wheel==0.48.0 regex==2024.11.6 requests==2.32.3 requests-mock==1.12.1 filelock==3.13.1 pyyaml==6.0.2 psutil==7.0.0 fsspec==2024.12.0 tqdm==4.67.1 +RUN HF_HUB_OFFLINE=0 TRANSFORMERS_OFFLINE=0 python -c 'exec('"'"'"""Standalone image-build program; never import target models or receive credentials."""\n\nfrom __future__ import annotations\n\nimport hashlib\nimport json\nfrom pathlib import Path\n\n\ndef fetch_assets(assets: list[dict], cache: Path) -> None:\n from huggingface_hub import get_hf_file_metadata, hf_hub_download, hf_hub_url\n\n manifests = []\n for asset in assets:\n sizes = {}\n for filename in asset["filenames"]:\n metadata = get_hf_file_metadata(\n hf_hub_url(asset["repo_id"], filename, revision=asset["revision"]), token=False\n )\n if metadata.commit_hash != asset["revision"] or metadata.size is None:\n raise ValueError("Hub metadata must resolve to the pinned revision and known size")\n sizes[filename] = metadata.size\n if sum(sizes.values()) > asset["max_bytes"]:\n raise ValueError(f"Asset exceeds download allowance: {asset[\'"'"'repo_id\'"'"']}")\n records = []\n for filename, size in sizes.items():\n path = Path(\n hf_hub_download(\n repo_id=asset["repo_id"],\n filename=filename,\n revision=asset["revision"],\n cache_dir=cache,\n token=False,\n )\n )\n if path.stat().st_size != size:\n raise ValueError("Downloaded asset size differs from pinned metadata")\n with path.open("rb") as stream:\n digest = hashlib.file_digest(stream, "sha256").hexdigest()\n records.append({"filename": filename, "bytes": size, "sha256": digest})\n # Upstream tests often omit revision. Their offline \'"'"'main\'"'"' lookup must\n # resolve to this explicit immutable pin, never the current Hub branch.\n ref = cache / ("models--" + asset["repo_id"].replace("/", "--")) / "refs/main"\n ref.parent.mkdir(parents=True, exist_ok=True)\n ref.write_text(asset["revision"])\n manifests.append({**asset, "files": records, "offline_main": asset["revision"]})\n cache.mkdir(parents=True, exist_ok=True)\n (cache / "tasksmith-assets.json").write_text(json.dumps(manifests, indent=2) + "\\n")\n\nfetch_assets(json.loads(\'"'"'[{"filenames": ["special_tokens_map.json", "tokenizer.json", "tokenizer.model", "tokenizer_config.json"], "max_bytes": 25165824, "repo_id": "hf-internal-testing/dummy-gemma", "revision": "9490194e9c2ab69809ef6b7c231c2836badd3930"}]\'"'"'), Path(\'"'"'/opt/tasksmith-hf/hub\'"'"'))\n'"'"')' +ENV HF_HOME=/opt/tasksmith-hf HF_HUB_CACHE=/opt/tasksmith-hf/hub +COPY . /workspace +RUN python -m pip install --no-cache-dir --no-deps --no-build-isolation -e . +RUN rm -rf /workspace/.git /root/.cache/pip +ENV PYTHONDONTWRITEBYTECODE=1 PYTEST_DISABLE_PLUGIN_AUTOLOAD=1 +ENV HF_HUB_OFFLINE=1 TRANSFORMERS_OFFLINE=1 HF_DATASETS_OFFLINE=1 diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/LICENSE b/tasks/tasksmith-48efdcc71e7d/tests/source/LICENSE new file mode 100644 index 0000000000000000000000000000000000000000..261eeb9e9f8b2b4b0d119366dda99c6fd7d35c64 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/LICENSE @@ -0,0 +1,201 @@ + Apache License + Version 2.0, January 2004 + http://www.apache.org/licenses/ + + TERMS AND CONDITIONS FOR USE, REPRODUCTION, AND DISTRIBUTION + + 1. Definitions. + + "License" shall mean the terms and conditions for use, reproduction, + and distribution as defined by Sections 1 through 9 of this document. + + "Licensor" shall mean the copyright owner or entity authorized by + the copyright owner that is granting the License. + + "Legal Entity" shall mean the union of the acting entity and all + other entities that control, are controlled by, or are under common + control with that entity. For the purposes of this definition, + "control" means (i) the power, direct or indirect, to cause the + direction or management of such entity, whether by contract or + otherwise, or (ii) ownership of fifty percent (50%) or more of the + outstanding shares, or (iii) beneficial ownership of such entity. + + "You" (or "Your") shall mean an individual or Legal Entity + exercising permissions granted by this License. + + "Source" form shall mean the preferred form for making modifications, + including but not limited to software source code, documentation + source, and configuration files. + + "Object" form shall mean any form resulting from mechanical + transformation or translation of a Source form, including but + not limited to compiled object code, generated documentation, + and conversions to other media types. + + "Work" shall mean the work of authorship, whether in Source or + Object form, made available under the License, as indicated by a + copyright notice that is included in or attached to the work + (an example is provided in the Appendix below). + + "Derivative Works" shall mean any work, whether in Source or Object + form, that is based on (or derived from) the Work and for which the + editorial revisions, annotations, elaborations, or other modifications + represent, as a whole, an original work of authorship. For the purposes + of this License, Derivative Works shall not include works that remain + separable from, or merely link (or bind by name) to the interfaces of, + the Work and Derivative Works thereof. + + "Contribution" shall mean any work of authorship, including + the original version of the Work and any modifications or additions + to that Work or Derivative Works thereof, that is intentionally + submitted to Licensor for inclusion in the Work by the copyright owner + or by an individual or Legal Entity authorized to submit on behalf of + the copyright owner. For the purposes of this definition, "submitted" + means any form of electronic, verbal, or written communication sent + to the Licensor or its representatives, including but not limited to + communication on electronic mailing lists, source code control systems, + and issue tracking systems that are managed by, or on behalf of, the + Licensor for the purpose of discussing and improving the Work, but + excluding communication that is conspicuously marked or otherwise + designated in writing by the copyright owner as "Not a Contribution." + + "Contributor" shall mean Licensor and any individual or Legal Entity + on behalf of whom a Contribution has been received by Licensor and + subsequently incorporated within the Work. + + 2. Grant of Copyright License. Subject to the terms and conditions of + this License, each Contributor hereby grants to You a perpetual, + worldwide, non-exclusive, no-charge, royalty-free, irrevocable + copyright license to reproduce, prepare Derivative Works of, + publicly display, publicly perform, sublicense, and distribute the + Work and such Derivative Works in Source or Object form. + + 3. Grant of Patent License. Subject to the terms and conditions of + this License, each Contributor hereby grants to You a perpetual, + worldwide, non-exclusive, no-charge, royalty-free, irrevocable + (except as stated in this section) patent license to make, have made, + use, offer to sell, sell, import, and otherwise transfer the Work, + where such license applies only to those patent claims licensable + by such Contributor that are necessarily infringed by their + Contribution(s) alone or by combination of their Contribution(s) + with the Work to which such Contribution(s) was submitted. If You + institute patent litigation against any entity (including a + cross-claim or counterclaim in a lawsuit) alleging that the Work + or a Contribution incorporated within the Work constitutes direct + or contributory patent infringement, then any patent licenses + granted to You under this License for that Work shall terminate + as of the date such litigation is filed. + + 4. Redistribution. You may reproduce and distribute copies of the + Work or Derivative Works thereof in any medium, with or without + modifications, and in Source or Object form, provided that You + meet the following conditions: + + (a) You must give any other recipients of the Work or + Derivative Works a copy of this License; and + + (b) You must cause any modified files to carry prominent notices + stating that You changed the files; and + + (c) You must retain, in the Source form of any Derivative Works + that You distribute, all copyright, patent, trademark, and + attribution notices from the Source form of the Work, + excluding those notices that do not pertain to any part of + the Derivative Works; and + + (d) If the Work includes a "NOTICE" text file as part of its + distribution, then any Derivative Works that You distribute must + include a readable copy of the attribution notices contained + within such NOTICE file, excluding those notices that do not + pertain to any part of the Derivative Works, in at least one + of the following places: within a NOTICE text file distributed + as part of the Derivative Works; within the Source form or + documentation, if provided along with the Derivative Works; or, + within a display generated by the Derivative Works, if and + wherever such third-party notices normally appear. The contents + of the NOTICE file are for informational purposes only and + do not modify the License. You may add Your own attribution + notices within Derivative Works that You distribute, alongside + or as an addendum to the NOTICE text from the Work, provided + that such additional attribution notices cannot be construed + as modifying the License. + + You may add Your own copyright statement to Your modifications and + may provide additional or different license terms and conditions + for use, reproduction, or distribution of Your modifications, or + for any such Derivative Works as a whole, provided Your use, + reproduction, and distribution of the Work otherwise complies with + the conditions stated in this License. + + 5. Submission of Contributions. Unless You explicitly state otherwise, + any Contribution intentionally submitted for inclusion in the Work + by You to the Licensor shall be under the terms and conditions of + this License, without any additional terms or conditions. + Notwithstanding the above, nothing herein shall supersede or modify + the terms of any separate license agreement you may have executed + with Licensor regarding such Contributions. + + 6. Trademarks. This License does not grant permission to use the trade + names, trademarks, service marks, or product names of the Licensor, + except as required for reasonable and customary use in describing the + origin of the Work and reproducing the content of the NOTICE file. + + 7. Disclaimer of Warranty. Unless required by applicable law or + agreed to in writing, Licensor provides the Work (and each + Contributor provides its Contributions) on an "AS IS" BASIS, + WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or + implied, including, without limitation, any warranties or conditions + of TITLE, NON-INFRINGEMENT, MERCHANTABILITY, or FITNESS FOR A + PARTICULAR PURPOSE. You are solely responsible for determining the + appropriateness of using or redistributing the Work and assume any + risks associated with Your exercise of permissions under this License. + + 8. Limitation of Liability. In no event and under no legal theory, + whether in tort (including negligence), contract, or otherwise, + unless required by applicable law (such as deliberate and grossly + negligent acts) or agreed to in writing, shall any Contributor be + liable to You for damages, including any direct, indirect, special, + incidental, or consequential damages of any character arising as a + result of this License or out of the use or inability to use the + Work (including but not limited to damages for loss of goodwill, + work stoppage, computer failure or malfunction, or any and all + other commercial damages or losses), even if such Contributor + has been advised of the possibility of such damages. + + 9. Accepting Warranty or Additional Liability. While redistributing + the Work or Derivative Works thereof, You may choose to offer, + and charge a fee for, acceptance of support, warranty, indemnity, + or other liability obligations and/or rights consistent with this + License. However, in accepting such obligations, You may act only + on Your own behalf and on Your sole responsibility, not on behalf + of any other Contributor, and only if You agree to indemnify, + defend, and hold each Contributor harmless for any liability + incurred by, or claims asserted against, such Contributor by reason + of your accepting any such warranty or additional liability. + + END OF TERMS AND CONDITIONS + + APPENDIX: How to apply the Apache License to your work. + + To apply the Apache License to your work, attach the following + boilerplate notice, with the fields enclosed by brackets "[]" + replaced with your own identifying information. (Don't include + the brackets!) The text should be enclosed in the appropriate + comment syntax for the file format. We also recommend that a + file or class name and description of purpose be included on the + same "printed page" as the copyright notice for easier + identification within third-party archives. + + Copyright [yyyy] [name of copyright owner] + + Licensed under the Apache License, Version 2.0 (the "License"); + you may not use this file except in compliance with the License. + You may obtain a copy of the License at + + http://www.apache.org/licenses/LICENSE-2.0 + + Unless required by applicable law or agreed to in writing, software + distributed under the License is distributed on an "AS IS" BASIS, + WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. + See the License for the specific language governing permissions and + limitations under the License. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/MANIFEST.in b/tasks/tasksmith-48efdcc71e7d/tests/source/MANIFEST.in new file mode 100644 index 0000000000000000000000000000000000000000..b22fe1a28a1ef881fdb36af3c30b14c0a5d10aa5 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/MANIFEST.in @@ -0,0 +1,2 @@ +include LICENSE +include src/diffusers/utils/model_card_template.md diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/Makefile b/tasks/tasksmith-48efdcc71e7d/tests/source/Makefile new file mode 100644 index 0000000000000000000000000000000000000000..9af2e8b1a5c9993411ffa06e7e48f9cfec3bd164 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/Makefile @@ -0,0 +1,96 @@ +.PHONY: deps_table_update modified_only_fixup extra_style_checks quality style fixup fix-copies test test-examples + +# make sure to test the local checkout in scripts and not the pre-installed one (don't use quotes!) +export PYTHONPATH = src + +check_dirs := examples scripts src tests utils benchmarks + +modified_only_fixup: + $(eval modified_py_files := $(shell python utils/get_modified_files.py $(check_dirs))) + @if test -n "$(modified_py_files)"; then \ + echo "Checking/fixing $(modified_py_files)"; \ + ruff check $(modified_py_files) --fix; \ + ruff format $(modified_py_files);\ + else \ + echo "No library .py files were modified"; \ + fi + +# Update src/diffusers/dependency_versions_table.py + +deps_table_update: + @python setup.py deps_table_update + +deps_table_check_updated: + @md5sum src/diffusers/dependency_versions_table.py > md5sum.saved + @python setup.py deps_table_update + @md5sum -c --quiet md5sum.saved || (printf "\nError: the version dependency table is outdated.\nPlease run 'make fixup' or 'make style' and commit the changes.\n\n" && exit 1) + @rm md5sum.saved + +# autogenerating code + +autogenerate_code: deps_table_update + +# Check that the repo is in a good state + +repo-consistency: + python utils/check_dummies.py + python utils/check_repo.py + python utils/check_inits.py + +# this target runs checks on all files + +quality: + ruff check $(check_dirs) setup.py + ruff format --check $(check_dirs) setup.py + doc-builder style src/diffusers docs/source --max_len 119 --check_only + python utils/check_doc_toc.py + +# Format source code automatically and check is there are any problems left that need manual fixing + +extra_style_checks: + python utils/custom_init_isort.py + python utils/check_doc_toc.py --fix_and_overwrite + +# this target runs checks on all files and potentially modifies some of them + +style: + ruff check $(check_dirs) setup.py --fix + ruff format $(check_dirs) setup.py + doc-builder style src/diffusers docs/source --max_len 119 + ${MAKE} autogenerate_code + ${MAKE} extra_style_checks + +# Super fast fix and check target that only works on relevant modified files since the branch was made + +fixup: modified_only_fixup extra_style_checks autogenerate_code repo-consistency + +# Make marked copies of snippets of codes conform to the original + +fix-copies: + python utils/check_copies.py --fix_and_overwrite + python utils/check_dummies.py --fix_and_overwrite + +# Run tests for the library + +test: + python -m pytest -n auto --dist=loadfile -s -v ./tests/ + +# Run tests for examples + +test-examples: + python -m pytest -n auto --dist=loadfile -s -v ./examples/ + + +# Release stuff + +pre-release: + python utils/release.py + +pre-patch: + python utils/release.py --patch + +post-release: + python utils/release.py --post_release + +post-patch: + python utils/release.py --post_release --patch diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/PHILOSOPHY.md b/tasks/tasksmith-48efdcc71e7d/tests/source/PHILOSOPHY.md new file mode 100644 index 0000000000000000000000000000000000000000..c646c61ec429020032cd51f0d17ac007b17edc48 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/PHILOSOPHY.md @@ -0,0 +1,110 @@ + + +# Philosophy + +🧨 Diffusers provides **state-of-the-art** pretrained diffusion models across multiple modalities. +Its purpose is to serve as a **modular toolbox** for both inference and training. + +We aim to build a library that stands the test of time and therefore take API design very seriously. + +In a nutshell, Diffusers is built to be a natural extension of PyTorch. Therefore, most of our design choices are based on [PyTorch's Design Principles](https://pytorch.org/docs/stable/community/design.html#pytorch-design-philosophy). Let's go over the most important ones: + +## Usability over Performance + +- While Diffusers has many built-in performance-enhancing features (see [Memory and Speed](https://huggingface.co/docs/diffusers/optimization/fp16)), models are always loaded with the highest precision and lowest optimization. Therefore, by default diffusion pipelines are always instantiated on CPU with float32 precision if not otherwise defined by the user. This ensures usability across different platforms and accelerators and means that no complex installations are required to run the library. +- Diffusers aims to be a **light-weight** package and therefore has very few required dependencies, but many soft dependencies that can improve performance (such as `accelerate`, `safetensors`, `onnx`, etc...). We strive to keep the library as lightweight as possible so that it can be added without much concern as a dependency on other packages. +- Diffusers prefers simple, self-explainable code over condensed, magic code. This means that short-hand code syntaxes such as lambda functions, and advanced PyTorch operators are often not desired. + +## Simple over easy + +As PyTorch states, **explicit is better than implicit** and **simple is better than complex**. This design philosophy is reflected in multiple parts of the library: +- We follow PyTorch's API with methods like [`DiffusionPipeline.to`](https://huggingface.co/docs/diffusers/main/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.to) to let the user handle device management. +- Raising concise error messages is preferred to silently correct erroneous input. Diffusers aims at teaching the user, rather than making the library as easy to use as possible. +- Complex model vs. scheduler logic is exposed instead of magically handled inside. Schedulers/Samplers are separated from diffusion models with minimal dependencies on each other. This forces the user to write the unrolled denoising loop. However, the separation allows for easier debugging and gives the user more control over adapting the denoising process or switching out diffusion models or schedulers. +- Separately trained components of the diffusion pipeline, *e.g.* the text encoder, the UNet, and the variational autoencoder, each has their own model class. This forces the user to handle the interaction between the different model components, and the serialization format separates the model components into different files. However, this allows for easier debugging and customization. DreamBooth or Textual Inversion training +is very simple thanks to Diffusers' ability to separate single components of the diffusion pipeline. + +## Tweakable, contributor-friendly over abstraction + +For large parts of the library, Diffusers adopts an important design principle of the [Transformers library](https://github.com/huggingface/transformers), which is to prefer copy-pasted code over hasty abstractions. This design principle is very opinionated and stands in stark contrast to popular design principles such as [Don't repeat yourself (DRY)](https://en.wikipedia.org/wiki/Don%27t_repeat_yourself). +In short, just like Transformers does for modeling files, Diffusers prefers to keep an extremely low level of abstraction and very self-contained code for pipelines and schedulers. +Functions, long code blocks, and even classes can be copied across multiple files which at first can look like a bad, sloppy design choice that makes the library unmaintainable. +**However**, this design has proven to be extremely successful for Transformers and makes a lot of sense for community-driven, open-source machine learning libraries because: +- Machine Learning is an extremely fast-moving field in which paradigms, model architectures, and algorithms are changing rapidly, which therefore makes it very difficult to define long-lasting code abstractions. +- Machine Learning practitioners like to be able to quickly tweak existing code for ideation and research and therefore prefer self-contained code over one that contains many abstractions. +- Open-source libraries rely on community contributions and therefore must build a library that is easy to contribute to. The more abstract the code, the more dependencies, the harder to read, and the harder to contribute to. Contributors simply stop contributing to very abstract libraries out of fear of breaking vital functionality. If contributing to a library cannot break other fundamental code, not only is it more inviting for potential new contributors, but it is also easier to review and contribute to multiple parts in parallel. + +At Hugging Face, we call this design the **single-file policy** which means that almost all of the code of a certain class should be written in a single, self-contained file. To read more about the philosophy, you can have a look +at [this blog post](https://huggingface.co/blog/transformers-design-philosophy). + +In Diffusers, we follow this philosophy for both pipelines and schedulers, but only partly for diffusion models. The reason we don't follow this design fully for diffusion models is because almost all diffusion pipelines, such +as [DDPM](https://huggingface.co/docs/diffusers/api/pipelines/ddpm), [Stable Diffusion](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion/overview#stable-diffusion-pipelines), [unCLIP (DALL·E 2)](https://huggingface.co/docs/diffusers/api/pipelines/unclip) and [Imagen](https://imagen.research.google/) all rely on the same diffusion model, the [UNet](https://huggingface.co/docs/diffusers/api/models/unet2d-cond). + +Great, now you should have generally understood why 🧨 Diffusers is designed the way it is 🤗. +We try to apply these design principles consistently across the library. Nevertheless, there are some minor exceptions to the philosophy or some unlucky design choices. If you have feedback regarding the design, we would ❤️ to hear it [directly on GitHub](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feedback.md&title=). + +## Design Philosophy in Details + +Now, let's look a bit into the nitty-gritty details of the design philosophy. Diffusers essentially consists of three major classes: [pipelines](https://github.com/huggingface/diffusers/tree/main/src/diffusers/pipelines), [models](https://github.com/huggingface/diffusers/tree/main/src/diffusers/models), and [schedulers](https://github.com/huggingface/diffusers/tree/main/src/diffusers/schedulers). +Let's walk through more detailed design decisions for each class. + +### Pipelines + +Pipelines are designed to be easy to use (therefore do not follow [*Simple over easy*](#simple-over-easy) 100%), are not feature complete, and should loosely be seen as examples of how to use [models](#models) and [schedulers](#schedulers) for inference. + +The following design principles are followed: +- Pipelines follow the single-file policy. All pipelines can be found in individual directories under src/diffusers/pipelines. One pipeline folder corresponds to one diffusion paper/project/release. Multiple pipeline files can be gathered in one pipeline folder, as it’s done for [`src/diffusers/pipelines/stable-diffusion`](https://github.com/huggingface/diffusers/tree/main/src/diffusers/pipelines/stable_diffusion). If pipelines share similar functionality, one can make use of the [# Copied from mechanism](https://github.com/huggingface/diffusers/blob/125d783076e5bd9785beb05367a2d2566843a271/src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_img2img.py#L251). +- Pipelines all inherit from [`DiffusionPipeline`]. +- Every pipeline consists of different model and scheduler components, that are documented in the [`model_index.json` file](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5/blob/main/model_index.json), are accessible under the same name as attributes of the pipeline and can be shared between pipelines with [`DiffusionPipeline.components`](https://huggingface.co/docs/diffusers/main/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.components) function. +- Every pipeline should be loadable via the [`DiffusionPipeline.from_pretrained`](https://huggingface.co/docs/diffusers/main/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.from_pretrained) function. +- Pipelines should be used **only** for inference. +- Pipelines should be very readable, self-explanatory, and easy to tweak. +- Pipelines should be designed to build on top of each other and be easy to integrate into higher-level APIs. +- Pipelines are **not** intended to be feature-complete user interfaces. For feature-complete user interfaces one should rather have a look at [InvokeAI](https://github.com/invoke-ai/InvokeAI), [Diffuzers](https://github.com/abhishekkrthakur/diffuzers), and [lama-cleaner](https://github.com/Sanster/lama-cleaner). +- Every pipeline should have one and only one way to run it via a `__call__` method. The naming of the `__call__` arguments should be shared across all pipelines. +- Pipelines should be named after the task they are intended to solve. +- In almost all cases, novel diffusion pipelines shall be implemented in a new pipeline folder/file. + +### Models + +Models are designed as configurable toolboxes that are natural extensions of [PyTorch's Module class](https://pytorch.org/docs/stable/generated/torch.nn.Module.html). They only partly follow the **single-file policy**. + +The following design principles are followed: +- Models correspond to **a type of model architecture**. *E.g.* the [`UNet2DConditionModel`] class is used for all UNet variations that expect 2D image inputs and are conditioned on some context. +- All models can be found in [`src/diffusers/models`](https://github.com/huggingface/diffusers/tree/main/src/diffusers/models) and every model architecture shall be defined in its file, e.g. [`unets/unet_2d_condition.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/unets/unet_2d_condition.py), [`transformers/transformer_2d.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/transformers/transformer_2d.py), etc... +- Models **do not** follow the single-file policy and should make use of smaller model building blocks, such as [`attention.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention.py), [`resnet.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/resnet.py), [`embeddings.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/embeddings.py), etc... **Note**: This is in stark contrast to Transformers' modeling files and shows that models do not really follow the single-file policy. +- Models intend to expose complexity, just like PyTorch's `Module` class, and give clear error messages. +- Models all inherit from `ModelMixin` and `ConfigMixin`. +- Models can be optimized for performance when it doesn’t demand major code changes, keep backward compatibility, and give significant memory or compute gain. +- Models should by default have the highest precision and lowest performance setting. +- To integrate new model checkpoints whose general architecture can be classified as an architecture that already exists in Diffusers, the existing model architecture shall be adapted to make it work with the new checkpoint. One should only create a new file if the model architecture is fundamentally different. +- Models should be designed to be easily extendable to future changes. This can be achieved by limiting public function arguments, configuration arguments, and "foreseeing" future changes, *e.g.* it is usually better to add `string` "...type" arguments that can easily be extended to new future types instead of boolean `is_..._type` arguments. Only the minimum amount of changes shall be made to existing architectures to make a new model checkpoint work. +- The model design is a difficult trade-off between keeping code readable and concise and supporting many model checkpoints. For most parts of the modeling code, classes shall be adapted for new model checkpoints, while there are some exceptions where it is preferred to add new classes to make sure the code is kept concise and +readable long-term, such as [UNet blocks](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/unets/unet_2d_blocks.py) and [Attention processors](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention_processor.py). + +### Schedulers + +Schedulers are responsible to guide the denoising process for inference as well as to define a noise schedule for training. They are designed as individual classes with loadable configuration files and strongly follow the **single-file policy**. + +The following design principles are followed: +- All schedulers are found in [`src/diffusers/schedulers`](https://github.com/huggingface/diffusers/tree/main/src/diffusers/schedulers). +- Schedulers are **not** allowed to import from large utils files and shall be kept very self-contained. +- One scheduler Python file corresponds to one scheduler algorithm (as might be defined in a paper). +- If schedulers share similar functionalities, we can make use of the `# Copied from` mechanism. +- Schedulers all inherit from `SchedulerMixin` and `ConfigMixin`. +- Schedulers can be easily swapped out with the [`ConfigMixin.from_config`](https://huggingface.co/docs/diffusers/main/en/api/configuration#diffusers.ConfigMixin.from_config) method as explained in detail [here](./docs/source/en/using-diffusers/schedulers.md). +- Every scheduler has to have a `set_num_inference_steps`, and a `step` function. `set_num_inference_steps(...)` has to be called before every denoising process, *i.e.* before `step(...)` is called. +- Every scheduler exposes the timesteps to be "looped over" via a `timesteps` attribute, which is an array of timesteps the model will be called upon. +- The `step(...)` function takes a predicted model output and the "current" sample (x_t) and returns the "previous", slightly more denoised sample (x_t-1). +- Given the complexity of diffusion schedulers, the `step` function does not expose all the complexity and can be a bit of a "black box". +- In almost all cases, novel schedulers shall be implemented in a new scheduling file. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/README.md b/tasks/tasksmith-48efdcc71e7d/tests/source/README.md new file mode 100644 index 0000000000000000000000000000000000000000..dac3b3598aaff2e6f8214d20a2a8b6a0158ba78a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/README.md @@ -0,0 +1,239 @@ + + +

+
+ +
+

+

+ GitHub + GitHub release + GitHub release + Contributor Covenant + X account +

+ +🤗 Diffusers is the go-to library for state-of-the-art pretrained diffusion models for generating images, audio, and even 3D structures of molecules. Whether you're looking for a simple inference solution or training your own diffusion models, 🤗 Diffusers is a modular toolbox that supports both. Our library is designed with a focus on [usability over performance](https://huggingface.co/docs/diffusers/conceptual/philosophy#usability-over-performance), [simple over easy](https://huggingface.co/docs/diffusers/conceptual/philosophy#simple-over-easy), and [customizability over abstractions](https://huggingface.co/docs/diffusers/conceptual/philosophy#tweakable-contributorfriendly-over-abstraction). + +🤗 Diffusers offers three core components: + +- State-of-the-art [diffusion pipelines](https://huggingface.co/docs/diffusers/api/pipelines/overview) that can be run in inference with just a few lines of code. +- Interchangeable noise [schedulers](https://huggingface.co/docs/diffusers/api/schedulers/overview) for different diffusion speeds and output quality. +- Pretrained [models](https://huggingface.co/docs/diffusers/api/models/overview) that can be used as building blocks, and combined with schedulers, for creating your own end-to-end diffusion systems. + +## Installation + +We recommend installing 🤗 Diffusers in a virtual environment from PyPI or Conda. For more details about installing [PyTorch](https://pytorch.org/get-started/locally/) and [Flax](https://flax.readthedocs.io/en/latest/#installation), please refer to their official documentation. + +### PyTorch + +With `pip` (official package): + +```bash +pip install --upgrade diffusers[torch] +``` + +With `conda` (maintained by the community): + +```sh +conda install -c conda-forge diffusers +``` + +### Flax + +With `pip` (official package): + +```bash +pip install --upgrade diffusers[flax] +``` + +### Apple Silicon (M1/M2) support + +Please refer to the [How to use Stable Diffusion in Apple Silicon](https://huggingface.co/docs/diffusers/optimization/mps) guide. + +## Quickstart + +Generating outputs is super easy with 🤗 Diffusers. To generate an image from text, use the `from_pretrained` method to load any pretrained diffusion model (browse the [Hub](https://huggingface.co/models?library=diffusers&sort=downloads) for 30,000+ checkpoints): + +```python +from diffusers import DiffusionPipeline +import torch + +pipeline = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16) +pipeline.to("cuda") +pipeline("An image of a squirrel in Picasso style").images[0] +``` + +You can also dig into the models and schedulers toolbox to build your own diffusion system: + +```python +from diffusers import DDPMScheduler, UNet2DModel +from PIL import Image +import torch + +scheduler = DDPMScheduler.from_pretrained("google/ddpm-cat-256") +model = UNet2DModel.from_pretrained("google/ddpm-cat-256").to("cuda") +scheduler.set_timesteps(50) + +sample_size = model.config.sample_size +noise = torch.randn((1, 3, sample_size, sample_size), device="cuda") +input = noise + +for t in scheduler.timesteps: + with torch.no_grad(): + noisy_residual = model(input, t).sample + prev_noisy_sample = scheduler.step(noisy_residual, t, input).prev_sample + input = prev_noisy_sample + +image = (input / 2 + 0.5).clamp(0, 1) +image = image.cpu().permute(0, 2, 3, 1).numpy()[0] +image = Image.fromarray((image * 255).round().astype("uint8")) +image +``` + +Check out the [Quickstart](https://huggingface.co/docs/diffusers/quicktour) to launch your diffusion journey today! + +## How to navigate the documentation + +| **Documentation** | **What can I learn?** | +|---------------------------------------------------------------------|-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------| +| [Tutorial](https://huggingface.co/docs/diffusers/tutorials/tutorial_overview) | A basic crash course for learning how to use the library's most important features like using models and schedulers to build your own diffusion system, and training your own diffusion model. | +| [Loading](https://huggingface.co/docs/diffusers/using-diffusers/loading) | Guides for how to load and configure all the components (pipelines, models, and schedulers) of the library, as well as how to use different schedulers. | +| [Pipelines for inference](https://huggingface.co/docs/diffusers/using-diffusers/overview_techniques) | Guides for how to use pipelines for different inference tasks, batched generation, controlling generated outputs and randomness, and how to contribute a pipeline to the library. | +| [Optimization](https://huggingface.co/docs/diffusers/optimization/fp16) | Guides for how to optimize your diffusion model to run faster and consume less memory. | +| [Training](https://huggingface.co/docs/diffusers/training/overview) | Guides for how to train a diffusion model for different tasks with different training techniques. | +## Contribution + +We ❤️ contributions from the open-source community! +If you want to contribute to this library, please check out our [Contribution guide](https://github.com/huggingface/diffusers/blob/main/CONTRIBUTING.md). +You can look out for [issues](https://github.com/huggingface/diffusers/issues) you'd like to tackle to contribute to the library. +- See [Good first issues](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22) for general opportunities to contribute +- See [New model/pipeline](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+pipeline%2Fmodel%22) to contribute exciting new diffusion models / diffusion pipelines +- See [New scheduler](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+scheduler%22) + +Also, say 👋 in our public Discord channel Join us on Discord. We discuss the hottest trends about diffusion models, help each other with contributions, personal projects or just hang out ☕. + + +## Popular Tasks & Pipelines + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + +
TaskPipeline🤗 Hub
Unconditional Image Generation DDPM google/ddpm-ema-church-256
Text-to-ImageStable Diffusion Text-to-Image stable-diffusion-v1-5/stable-diffusion-v1-5
Text-to-ImageunCLIP kakaobrain/karlo-v1-alpha
Text-to-ImageDeepFloyd IF DeepFloyd/IF-I-XL-v1.0
Text-to-ImageKandinsky kandinsky-community/kandinsky-2-2-decoder
Text-guided Image-to-ImageControlNet lllyasviel/sd-controlnet-canny
Text-guided Image-to-ImageInstructPix2Pix timbrooks/instruct-pix2pix
Text-guided Image-to-ImageStable Diffusion Image-to-Image stable-diffusion-v1-5/stable-diffusion-v1-5
Text-guided Image InpaintingStable Diffusion Inpainting runwayml/stable-diffusion-inpainting
Image VariationStable Diffusion Image Variation lambdalabs/sd-image-variations-diffusers
Super ResolutionStable Diffusion Upscale stabilityai/stable-diffusion-x4-upscaler
Super ResolutionStable Diffusion Latent Upscale stabilityai/sd-x2-latent-upscaler
+ +## Popular libraries using 🧨 Diffusers + +- https://github.com/microsoft/TaskMatrix +- https://github.com/invoke-ai/InvokeAI +- https://github.com/InstantID/InstantID +- https://github.com/apple/ml-stable-diffusion +- https://github.com/Sanster/lama-cleaner +- https://github.com/IDEA-Research/Grounded-Segment-Anything +- https://github.com/ashawkey/stable-dreamfusion +- https://github.com/deep-floyd/IF +- https://github.com/bentoml/BentoML +- https://github.com/bmaltais/kohya_ss +- +14,000 other amazing GitHub repositories 💪 + +Thank you for using us ❤️. + +## Credits + +This library concretizes previous work by many different authors and would not have been possible without their great research and implementations. We'd like to thank, in particular, the following implementations which have helped us in our development and without which the API could not have been as polished today: + +- @CompVis' latent diffusion models library, available [here](https://github.com/CompVis/latent-diffusion) +- @hojonathanho original DDPM implementation, available [here](https://github.com/hojonathanho/diffusion) as well as the extremely useful translation into PyTorch by @pesser, available [here](https://github.com/pesser/pytorch_diffusion) +- @ermongroup's DDIM implementation, available [here](https://github.com/ermongroup/ddim) +- @yang-song's Score-VE and Score-VP implementations, available [here](https://github.com/yang-song/score_sde_pytorch) + +We also want to thank @heejkoo for the very helpful overview of papers, code and resources on diffusion models, available [here](https://github.com/heejkoo/Awesome-Diffusion-Models) as well as @crowsonkb and @rromb for useful discussions and insights. + +## Citation + +```bibtex +@misc{von-platen-etal-2022-diffusers, + author = {Patrick von Platen and Suraj Patil and Anton Lozhkov and Pedro Cuenca and Nathan Lambert and Kashif Rasul and Mishig Davaadorj and Dhruv Nair and Sayak Paul and William Berman and Yiyi Xu and Steven Liu and Thomas Wolf}, + title = {Diffusers: State-of-the-art diffusion models}, + year = {2022}, + publisher = {GitHub}, + journal = {GitHub repository}, + howpublished = {\url{https://github.com/huggingface/diffusers}} +} +``` diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/_typos.toml b/tasks/tasksmith-48efdcc71e7d/tests/source/_typos.toml new file mode 100644 index 0000000000000000000000000000000000000000..551099f981e7885fbda9ed28e297bace0e13407b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/_typos.toml @@ -0,0 +1,13 @@ +# Files for typos +# Instruction: https://github.com/marketplace/actions/typos-action#getting-started + +[default.extend-identifiers] + +[default.extend-words] +NIN="NIN" # NIN is used in scripts/convert_ncsnpp_original_checkpoint_to_diffusers.py +nd="np" # nd may be np (numpy) +parms="parms" # parms is used in scripts/convert_original_stable_diffusion_to_diffusers.py + + +[files] +extend-exclude = ["_typos.toml"] diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/base_classes.py b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/base_classes.py new file mode 100644 index 0000000000000000000000000000000000000000..45bf65c93c93a3a77d5b2e4b321b19a4cf9cd63f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/base_classes.py @@ -0,0 +1,346 @@ +import os +import sys + +import torch + +from diffusers import ( + AutoPipelineForImage2Image, + AutoPipelineForInpainting, + AutoPipelineForText2Image, + ControlNetModel, + LCMScheduler, + StableDiffusionAdapterPipeline, + StableDiffusionControlNetPipeline, + StableDiffusionXLAdapterPipeline, + StableDiffusionXLControlNetPipeline, + T2IAdapter, + WuerstchenCombinedPipeline, +) +from diffusers.utils import load_image + + +sys.path.append(".") + +from utils import ( # noqa: E402 + BASE_PATH, + PROMPT, + BenchmarkInfo, + benchmark_fn, + bytes_to_giga_bytes, + flush, + generate_csv_dict, + write_to_csv, +) + + +RESOLUTION_MAPPING = { + "Lykon/DreamShaper": (512, 512), + "lllyasviel/sd-controlnet-canny": (512, 512), + "diffusers/controlnet-canny-sdxl-1.0": (1024, 1024), + "TencentARC/t2iadapter_canny_sd14v1": (512, 512), + "TencentARC/t2i-adapter-canny-sdxl-1.0": (1024, 1024), + "stabilityai/stable-diffusion-2-1": (768, 768), + "stabilityai/stable-diffusion-xl-base-1.0": (1024, 1024), + "stabilityai/stable-diffusion-xl-refiner-1.0": (1024, 1024), + "stabilityai/sdxl-turbo": (512, 512), +} + + +class BaseBenchmak: + pipeline_class = None + + def __init__(self, args): + super().__init__() + + def run_inference(self, args): + raise NotImplementedError + + def benchmark(self, args): + raise NotImplementedError + + def get_result_filepath(self, args): + pipeline_class_name = str(self.pipe.__class__.__name__) + name = ( + args.ckpt.replace("/", "_") + + "_" + + pipeline_class_name + + f"-bs@{args.batch_size}-steps@{args.num_inference_steps}-mco@{args.model_cpu_offload}-compile@{args.run_compile}.csv" + ) + filepath = os.path.join(BASE_PATH, name) + return filepath + + +class TextToImageBenchmark(BaseBenchmak): + pipeline_class = AutoPipelineForText2Image + + def __init__(self, args): + pipe = self.pipeline_class.from_pretrained(args.ckpt, torch_dtype=torch.float16) + pipe = pipe.to("cuda") + + if args.run_compile: + if not isinstance(pipe, WuerstchenCombinedPipeline): + pipe.unet.to(memory_format=torch.channels_last) + print("Run torch compile") + pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True) + + if hasattr(pipe, "movq") and getattr(pipe, "movq", None) is not None: + pipe.movq.to(memory_format=torch.channels_last) + pipe.movq = torch.compile(pipe.movq, mode="reduce-overhead", fullgraph=True) + else: + print("Run torch compile") + pipe.decoder = torch.compile(pipe.decoder, mode="reduce-overhead", fullgraph=True) + pipe.vqgan = torch.compile(pipe.vqgan, mode="reduce-overhead", fullgraph=True) + + pipe.set_progress_bar_config(disable=True) + self.pipe = pipe + + def run_inference(self, pipe, args): + _ = pipe( + prompt=PROMPT, + num_inference_steps=args.num_inference_steps, + num_images_per_prompt=args.batch_size, + ) + + def benchmark(self, args): + flush() + + print(f"[INFO] {self.pipe.__class__.__name__}: Running benchmark with: {vars(args)}\n") + + time = benchmark_fn(self.run_inference, self.pipe, args) # in seconds. + memory = bytes_to_giga_bytes(torch.cuda.max_memory_allocated()) # in GBs. + benchmark_info = BenchmarkInfo(time=time, memory=memory) + + pipeline_class_name = str(self.pipe.__class__.__name__) + flush() + csv_dict = generate_csv_dict( + pipeline_cls=pipeline_class_name, ckpt=args.ckpt, args=args, benchmark_info=benchmark_info + ) + filepath = self.get_result_filepath(args) + write_to_csv(filepath, csv_dict) + print(f"Logs written to: {filepath}") + flush() + + +class TurboTextToImageBenchmark(TextToImageBenchmark): + def __init__(self, args): + super().__init__(args) + + def run_inference(self, pipe, args): + _ = pipe( + prompt=PROMPT, + num_inference_steps=args.num_inference_steps, + num_images_per_prompt=args.batch_size, + guidance_scale=0.0, + ) + + +class LCMLoRATextToImageBenchmark(TextToImageBenchmark): + lora_id = "latent-consistency/lcm-lora-sdxl" + + def __init__(self, args): + super().__init__(args) + self.pipe.load_lora_weights(self.lora_id) + self.pipe.fuse_lora() + self.pipe.unload_lora_weights() + self.pipe.scheduler = LCMScheduler.from_config(self.pipe.scheduler.config) + + def get_result_filepath(self, args): + pipeline_class_name = str(self.pipe.__class__.__name__) + name = ( + self.lora_id.replace("/", "_") + + "_" + + pipeline_class_name + + f"-bs@{args.batch_size}-steps@{args.num_inference_steps}-mco@{args.model_cpu_offload}-compile@{args.run_compile}.csv" + ) + filepath = os.path.join(BASE_PATH, name) + return filepath + + def run_inference(self, pipe, args): + _ = pipe( + prompt=PROMPT, + num_inference_steps=args.num_inference_steps, + num_images_per_prompt=args.batch_size, + guidance_scale=1.0, + ) + + def benchmark(self, args): + flush() + + print(f"[INFO] {self.pipe.__class__.__name__}: Running benchmark with: {vars(args)}\n") + + time = benchmark_fn(self.run_inference, self.pipe, args) # in seconds. + memory = bytes_to_giga_bytes(torch.cuda.max_memory_allocated()) # in GBs. + benchmark_info = BenchmarkInfo(time=time, memory=memory) + + pipeline_class_name = str(self.pipe.__class__.__name__) + flush() + csv_dict = generate_csv_dict( + pipeline_cls=pipeline_class_name, ckpt=self.lora_id, args=args, benchmark_info=benchmark_info + ) + filepath = self.get_result_filepath(args) + write_to_csv(filepath, csv_dict) + print(f"Logs written to: {filepath}") + flush() + + +class ImageToImageBenchmark(TextToImageBenchmark): + pipeline_class = AutoPipelineForImage2Image + url = "https://huggingface.co/datasets/diffusers/docs-images/resolve/main/benchmarking/1665_Girl_with_a_Pearl_Earring.jpg" + image = load_image(url).convert("RGB") + + def __init__(self, args): + super().__init__(args) + self.image = self.image.resize(RESOLUTION_MAPPING[args.ckpt]) + + def run_inference(self, pipe, args): + _ = pipe( + prompt=PROMPT, + image=self.image, + num_inference_steps=args.num_inference_steps, + num_images_per_prompt=args.batch_size, + ) + + +class TurboImageToImageBenchmark(ImageToImageBenchmark): + def __init__(self, args): + super().__init__(args) + + def run_inference(self, pipe, args): + _ = pipe( + prompt=PROMPT, + image=self.image, + num_inference_steps=args.num_inference_steps, + num_images_per_prompt=args.batch_size, + guidance_scale=0.0, + strength=0.5, + ) + + +class InpaintingBenchmark(ImageToImageBenchmark): + pipeline_class = AutoPipelineForInpainting + mask_url = "https://huggingface.co/datasets/diffusers/docs-images/resolve/main/benchmarking/overture-creations-5sI6fQgYIuo_mask.png" + mask = load_image(mask_url).convert("RGB") + + def __init__(self, args): + super().__init__(args) + self.image = self.image.resize(RESOLUTION_MAPPING[args.ckpt]) + self.mask = self.mask.resize(RESOLUTION_MAPPING[args.ckpt]) + + def run_inference(self, pipe, args): + _ = pipe( + prompt=PROMPT, + image=self.image, + mask_image=self.mask, + num_inference_steps=args.num_inference_steps, + num_images_per_prompt=args.batch_size, + ) + + +class IPAdapterTextToImageBenchmark(TextToImageBenchmark): + url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/load_neg_embed.png" + image = load_image(url) + + def __init__(self, args): + pipe = self.pipeline_class.from_pretrained(args.ckpt, torch_dtype=torch.float16).to("cuda") + pipe.load_ip_adapter( + args.ip_adapter_id[0], + subfolder="models" if "sdxl" not in args.ip_adapter_id[1] else "sdxl_models", + weight_name=args.ip_adapter_id[1], + ) + + if args.run_compile: + pipe.unet.to(memory_format=torch.channels_last) + print("Run torch compile") + pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True) + + pipe.set_progress_bar_config(disable=True) + self.pipe = pipe + + def run_inference(self, pipe, args): + _ = pipe( + prompt=PROMPT, + ip_adapter_image=self.image, + num_inference_steps=args.num_inference_steps, + num_images_per_prompt=args.batch_size, + ) + + +class ControlNetBenchmark(TextToImageBenchmark): + pipeline_class = StableDiffusionControlNetPipeline + aux_network_class = ControlNetModel + root_ckpt = "Lykon/DreamShaper" + + url = "https://huggingface.co/datasets/diffusers/docs-images/resolve/main/benchmarking/canny_image_condition.png" + image = load_image(url).convert("RGB") + + def __init__(self, args): + aux_network = self.aux_network_class.from_pretrained(args.ckpt, torch_dtype=torch.float16) + pipe = self.pipeline_class.from_pretrained(self.root_ckpt, controlnet=aux_network, torch_dtype=torch.float16) + pipe = pipe.to("cuda") + + pipe.set_progress_bar_config(disable=True) + self.pipe = pipe + + if args.run_compile: + pipe.unet.to(memory_format=torch.channels_last) + pipe.controlnet.to(memory_format=torch.channels_last) + + print("Run torch compile") + pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True) + pipe.controlnet = torch.compile(pipe.controlnet, mode="reduce-overhead", fullgraph=True) + + self.image = self.image.resize(RESOLUTION_MAPPING[args.ckpt]) + + def run_inference(self, pipe, args): + _ = pipe( + prompt=PROMPT, + image=self.image, + num_inference_steps=args.num_inference_steps, + num_images_per_prompt=args.batch_size, + ) + + +class ControlNetSDXLBenchmark(ControlNetBenchmark): + pipeline_class = StableDiffusionXLControlNetPipeline + root_ckpt = "stabilityai/stable-diffusion-xl-base-1.0" + + def __init__(self, args): + super().__init__(args) + + +class T2IAdapterBenchmark(ControlNetBenchmark): + pipeline_class = StableDiffusionAdapterPipeline + aux_network_class = T2IAdapter + root_ckpt = "Lykon/DreamShaper" + + url = "https://huggingface.co/datasets/diffusers/docs-images/resolve/main/benchmarking/canny_for_adapter.png" + image = load_image(url).convert("L") + + def __init__(self, args): + aux_network = self.aux_network_class.from_pretrained(args.ckpt, torch_dtype=torch.float16) + pipe = self.pipeline_class.from_pretrained(self.root_ckpt, adapter=aux_network, torch_dtype=torch.float16) + pipe = pipe.to("cuda") + + pipe.set_progress_bar_config(disable=True) + self.pipe = pipe + + if args.run_compile: + pipe.unet.to(memory_format=torch.channels_last) + pipe.adapter.to(memory_format=torch.channels_last) + + print("Run torch compile") + pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True) + pipe.adapter = torch.compile(pipe.adapter, mode="reduce-overhead", fullgraph=True) + + self.image = self.image.resize(RESOLUTION_MAPPING[args.ckpt]) + + +class T2IAdapterSDXLBenchmark(T2IAdapterBenchmark): + pipeline_class = StableDiffusionXLAdapterPipeline + root_ckpt = "stabilityai/stable-diffusion-xl-base-1.0" + + url = "https://huggingface.co/datasets/diffusers/docs-images/resolve/main/benchmarking/canny_for_adapter_sdxl.png" + image = load_image(url) + + def __init__(self, args): + super().__init__(args) diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_controlnet.py b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_controlnet.py new file mode 100644 index 0000000000000000000000000000000000000000..9217004461dc9352b1b9e6cda698dd866177eb67 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_controlnet.py @@ -0,0 +1,26 @@ +import argparse +import sys + + +sys.path.append(".") +from base_classes import ControlNetBenchmark, ControlNetSDXLBenchmark # noqa: E402 + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument( + "--ckpt", + type=str, + default="lllyasviel/sd-controlnet-canny", + choices=["lllyasviel/sd-controlnet-canny", "diffusers/controlnet-canny-sdxl-1.0"], + ) + parser.add_argument("--batch_size", type=int, default=1) + parser.add_argument("--num_inference_steps", type=int, default=50) + parser.add_argument("--model_cpu_offload", action="store_true") + parser.add_argument("--run_compile", action="store_true") + args = parser.parse_args() + + benchmark_pipe = ( + ControlNetBenchmark(args) if args.ckpt == "lllyasviel/sd-controlnet-canny" else ControlNetSDXLBenchmark(args) + ) + benchmark_pipe.benchmark(args) diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_ip_adapters.py b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_ip_adapters.py new file mode 100644 index 0000000000000000000000000000000000000000..9a31a21fc60ddd2d041d7896ee4144d1766fcc01 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_ip_adapters.py @@ -0,0 +1,33 @@ +import argparse +import sys + + +sys.path.append(".") +from base_classes import IPAdapterTextToImageBenchmark # noqa: E402 + + +IP_ADAPTER_CKPTS = { + # because original SD v1.5 has been taken down. + "Lykon/DreamShaper": ("h94/IP-Adapter", "ip-adapter_sd15.bin"), + "stabilityai/stable-diffusion-xl-base-1.0": ("h94/IP-Adapter", "ip-adapter_sdxl.bin"), +} + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument( + "--ckpt", + type=str, + default="rstabilityai/stable-diffusion-xl-base-1.0", + choices=list(IP_ADAPTER_CKPTS.keys()), + ) + parser.add_argument("--batch_size", type=int, default=1) + parser.add_argument("--num_inference_steps", type=int, default=50) + parser.add_argument("--model_cpu_offload", action="store_true") + parser.add_argument("--run_compile", action="store_true") + args = parser.parse_args() + + args.ip_adapter_id = IP_ADAPTER_CKPTS[args.ckpt] + benchmark_pipe = IPAdapterTextToImageBenchmark(args) + args.ckpt = f"{args.ckpt} (IP-Adapter)" + benchmark_pipe.benchmark(args) diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_sd_img.py b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_sd_img.py new file mode 100644 index 0000000000000000000000000000000000000000..772befe8795fb933fdb7831565eb28848e642af2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_sd_img.py @@ -0,0 +1,29 @@ +import argparse +import sys + + +sys.path.append(".") +from base_classes import ImageToImageBenchmark, TurboImageToImageBenchmark # noqa: E402 + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument( + "--ckpt", + type=str, + default="Lykon/DreamShaper", + choices=[ + "Lykon/DreamShaper", + "stabilityai/stable-diffusion-2-1", + "stabilityai/stable-diffusion-xl-refiner-1.0", + "stabilityai/sdxl-turbo", + ], + ) + parser.add_argument("--batch_size", type=int, default=1) + parser.add_argument("--num_inference_steps", type=int, default=50) + parser.add_argument("--model_cpu_offload", action="store_true") + parser.add_argument("--run_compile", action="store_true") + args = parser.parse_args() + + benchmark_pipe = ImageToImageBenchmark(args) if "turbo" not in args.ckpt else TurboImageToImageBenchmark(args) + benchmark_pipe.benchmark(args) diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_sd_inpainting.py b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_sd_inpainting.py new file mode 100644 index 0000000000000000000000000000000000000000..143adcb0d87c7a9cf9c8ae0d19581fd48f9ac4c8 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_sd_inpainting.py @@ -0,0 +1,28 @@ +import argparse +import sys + + +sys.path.append(".") +from base_classes import InpaintingBenchmark # noqa: E402 + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument( + "--ckpt", + type=str, + default="Lykon/DreamShaper", + choices=[ + "Lykon/DreamShaper", + "stabilityai/stable-diffusion-2-1", + "stabilityai/stable-diffusion-xl-base-1.0", + ], + ) + parser.add_argument("--batch_size", type=int, default=1) + parser.add_argument("--num_inference_steps", type=int, default=50) + parser.add_argument("--model_cpu_offload", action="store_true") + parser.add_argument("--run_compile", action="store_true") + args = parser.parse_args() + + benchmark_pipe = InpaintingBenchmark(args) + benchmark_pipe.benchmark(args) diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_t2i_adapter.py b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_t2i_adapter.py new file mode 100644 index 0000000000000000000000000000000000000000..44b04b470ea65d5f3318bee21bb107c7b4b2b2f9 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_t2i_adapter.py @@ -0,0 +1,28 @@ +import argparse +import sys + + +sys.path.append(".") +from base_classes import T2IAdapterBenchmark, T2IAdapterSDXLBenchmark # noqa: E402 + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument( + "--ckpt", + type=str, + default="TencentARC/t2iadapter_canny_sd14v1", + choices=["TencentARC/t2iadapter_canny_sd14v1", "TencentARC/t2i-adapter-canny-sdxl-1.0"], + ) + parser.add_argument("--batch_size", type=int, default=1) + parser.add_argument("--num_inference_steps", type=int, default=50) + parser.add_argument("--model_cpu_offload", action="store_true") + parser.add_argument("--run_compile", action="store_true") + args = parser.parse_args() + + benchmark_pipe = ( + T2IAdapterBenchmark(args) + if args.ckpt == "TencentARC/t2iadapter_canny_sd14v1" + else T2IAdapterSDXLBenchmark(args) + ) + benchmark_pipe.benchmark(args) diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_t2i_lcm_lora.py b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_t2i_lcm_lora.py new file mode 100644 index 0000000000000000000000000000000000000000..957e0a463e28fccc51fe32cd975f3d5234cfd1f2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_t2i_lcm_lora.py @@ -0,0 +1,23 @@ +import argparse +import sys + + +sys.path.append(".") +from base_classes import LCMLoRATextToImageBenchmark # noqa: E402 + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument( + "--ckpt", + type=str, + default="stabilityai/stable-diffusion-xl-base-1.0", + ) + parser.add_argument("--batch_size", type=int, default=1) + parser.add_argument("--num_inference_steps", type=int, default=4) + parser.add_argument("--model_cpu_offload", action="store_true") + parser.add_argument("--run_compile", action="store_true") + args = parser.parse_args() + + benchmark_pipe = LCMLoRATextToImageBenchmark(args) + benchmark_pipe.benchmark(args) diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_text_to_image.py b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_text_to_image.py new file mode 100644 index 0000000000000000000000000000000000000000..ddc7fb2676a5c6090ce08e4488f5ca697c4329aa --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/benchmark_text_to_image.py @@ -0,0 +1,40 @@ +import argparse +import sys + + +sys.path.append(".") +from base_classes import TextToImageBenchmark, TurboTextToImageBenchmark # noqa: E402 + + +ALL_T2I_CKPTS = [ + "Lykon/DreamShaper", + "segmind/SSD-1B", + "stabilityai/stable-diffusion-xl-base-1.0", + "kandinsky-community/kandinsky-2-2-decoder", + "warp-ai/wuerstchen", + "stabilityai/sdxl-turbo", +] + + +if __name__ == "__main__": + parser = argparse.ArgumentParser() + parser.add_argument( + "--ckpt", + type=str, + default="Lykon/DreamShaper", + choices=ALL_T2I_CKPTS, + ) + parser.add_argument("--batch_size", type=int, default=1) + parser.add_argument("--num_inference_steps", type=int, default=50) + parser.add_argument("--model_cpu_offload", action="store_true") + parser.add_argument("--run_compile", action="store_true") + args = parser.parse_args() + + benchmark_cls = None + if "turbo" in args.ckpt: + benchmark_cls = TurboTextToImageBenchmark + else: + benchmark_cls = TextToImageBenchmark + + benchmark_pipe = benchmark_cls(args) + benchmark_pipe.benchmark(args) diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/push_results.py b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/push_results.py new file mode 100644 index 0000000000000000000000000000000000000000..71cd60f32c0fa9ddbf10f73dc3c9ee3e1531e07c --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/push_results.py @@ -0,0 +1,72 @@ +import glob +import sys + +import pandas as pd +from huggingface_hub import hf_hub_download, upload_file +from huggingface_hub.utils import EntryNotFoundError + + +sys.path.append(".") +from utils import BASE_PATH, FINAL_CSV_FILE, GITHUB_SHA, REPO_ID, collate_csv # noqa: E402 + + +def has_previous_benchmark() -> str: + csv_path = None + try: + csv_path = hf_hub_download(repo_id=REPO_ID, repo_type="dataset", filename=FINAL_CSV_FILE) + except EntryNotFoundError: + csv_path = None + return csv_path + + +def filter_float(value): + if isinstance(value, str): + return float(value.split()[0]) + return value + + +def push_to_hf_dataset(): + all_csvs = sorted(glob.glob(f"{BASE_PATH}/*.csv")) + collate_csv(all_csvs, FINAL_CSV_FILE) + + # If there's an existing benchmark file, we should report the changes. + csv_path = has_previous_benchmark() + if csv_path is not None: + current_results = pd.read_csv(FINAL_CSV_FILE) + previous_results = pd.read_csv(csv_path) + + numeric_columns = current_results.select_dtypes(include=["float64", "int64"]).columns + numeric_columns = [ + c for c in numeric_columns if c not in ["batch_size", "num_inference_steps", "actual_gpu_memory (gbs)"] + ] + + for column in numeric_columns: + previous_results[column] = previous_results[column].map(lambda x: filter_float(x)) + + # Calculate the percentage change + current_results[column] = current_results[column].astype(float) + previous_results[column] = previous_results[column].astype(float) + percent_change = ((current_results[column] - previous_results[column]) / previous_results[column]) * 100 + + # Format the values with '+' or '-' sign and append to original values + current_results[column] = current_results[column].map(str) + percent_change.map( + lambda x: f" ({'+' if x > 0 else ''}{x:.2f}%)" + ) + # There might be newly added rows. So, filter out the NaNs. + current_results[column] = current_results[column].map(lambda x: x.replace(" (nan%)", "")) + + # Overwrite the current result file. + current_results.to_csv(FINAL_CSV_FILE, index=False) + + commit_message = f"upload from sha: {GITHUB_SHA}" if GITHUB_SHA is not None else "upload benchmark results" + upload_file( + repo_id=REPO_ID, + path_in_repo=FINAL_CSV_FILE, + path_or_fileobj=FINAL_CSV_FILE, + repo_type="dataset", + commit_message=commit_message, + ) + + +if __name__ == "__main__": + push_to_hf_dataset() diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/run_all.py b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/run_all.py new file mode 100644 index 0000000000000000000000000000000000000000..c9932cc71c38513a301854a5ad227a2e3ec28d30 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/run_all.py @@ -0,0 +1,101 @@ +import glob +import subprocess +import sys +from typing import List + + +sys.path.append(".") +from benchmark_text_to_image import ALL_T2I_CKPTS # noqa: E402 + + +PATTERN = "benchmark_*.py" + + +class SubprocessCallException(Exception): + pass + + +# Taken from `test_examples_utils.py` +def run_command(command: List[str], return_stdout=False): + """ + Runs `command` with `subprocess.check_output` and will potentially return the `stdout`. Will also properly capture + if an error occurred while running `command` + """ + try: + output = subprocess.check_output(command, stderr=subprocess.STDOUT) + if return_stdout: + if hasattr(output, "decode"): + output = output.decode("utf-8") + return output + except subprocess.CalledProcessError as e: + raise SubprocessCallException( + f"Command `{' '.join(command)}` failed with the following error:\n\n{e.output.decode()}" + ) from e + + +def main(): + python_files = glob.glob(PATTERN) + + for file in python_files: + print(f"****** Running file: {file} ******") + + # Run with canonical settings. + if file != "benchmark_text_to_image.py" and file != "benchmark_ip_adapters.py": + command = f"python {file}" + run_command(command.split()) + + command += " --run_compile" + run_command(command.split()) + + # Run variants. + for file in python_files: + # See: https://github.com/pytorch/pytorch/issues/129637 + if file == "benchmark_ip_adapters.py": + continue + + if file == "benchmark_text_to_image.py": + for ckpt in ALL_T2I_CKPTS: + command = f"python {file} --ckpt {ckpt}" + + if "turbo" in ckpt: + command += " --num_inference_steps 1" + + run_command(command.split()) + + command += " --run_compile" + run_command(command.split()) + + elif file == "benchmark_sd_img.py": + for ckpt in ["stabilityai/stable-diffusion-xl-refiner-1.0", "stabilityai/sdxl-turbo"]: + command = f"python {file} --ckpt {ckpt}" + + if ckpt == "stabilityai/sdxl-turbo": + command += " --num_inference_steps 2" + + run_command(command.split()) + command += " --run_compile" + run_command(command.split()) + + elif file in ["benchmark_sd_inpainting.py", "benchmark_ip_adapters.py"]: + sdxl_ckpt = "stabilityai/stable-diffusion-xl-base-1.0" + command = f"python {file} --ckpt {sdxl_ckpt}" + run_command(command.split()) + + command += " --run_compile" + run_command(command.split()) + + elif file in ["benchmark_controlnet.py", "benchmark_t2i_adapter.py"]: + sdxl_ckpt = ( + "diffusers/controlnet-canny-sdxl-1.0" + if "controlnet" in file + else "TencentARC/t2i-adapter-canny-sdxl-1.0" + ) + command = f"python {file} --ckpt {sdxl_ckpt}" + run_command(command.split()) + + command += " --run_compile" + run_command(command.split()) + + +if __name__ == "__main__": + main() diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/utils.py b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/utils.py new file mode 100644 index 0000000000000000000000000000000000000000..5fce920ac6c3549e3654b1cfb2f0e79096aa019d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/benchmarks/utils.py @@ -0,0 +1,98 @@ +import argparse +import csv +import gc +import os +from dataclasses import dataclass +from typing import Dict, List, Union + +import torch +import torch.utils.benchmark as benchmark + + +GITHUB_SHA = os.getenv("GITHUB_SHA", None) +BENCHMARK_FIELDS = [ + "pipeline_cls", + "ckpt_id", + "batch_size", + "num_inference_steps", + "model_cpu_offload", + "run_compile", + "time (secs)", + "memory (gbs)", + "actual_gpu_memory (gbs)", + "github_sha", +] + +PROMPT = "ghibli style, a fantasy landscape with castles" +BASE_PATH = os.getenv("BASE_PATH", ".") +TOTAL_GPU_MEMORY = float(os.getenv("TOTAL_GPU_MEMORY", torch.cuda.get_device_properties(0).total_memory / (1024**3))) + +REPO_ID = "diffusers/benchmarks" +FINAL_CSV_FILE = "collated_results.csv" + + +@dataclass +class BenchmarkInfo: + time: float + memory: float + + +def flush(): + """Wipes off memory.""" + gc.collect() + torch.cuda.empty_cache() + torch.cuda.reset_max_memory_allocated() + torch.cuda.reset_peak_memory_stats() + + +def bytes_to_giga_bytes(bytes): + return f"{(bytes / 1024 / 1024 / 1024):.3f}" + + +def benchmark_fn(f, *args, **kwargs): + t0 = benchmark.Timer( + stmt="f(*args, **kwargs)", + globals={"args": args, "kwargs": kwargs, "f": f}, + num_threads=torch.get_num_threads(), + ) + return f"{(t0.blocked_autorange().mean):.3f}" + + +def generate_csv_dict( + pipeline_cls: str, ckpt: str, args: argparse.Namespace, benchmark_info: BenchmarkInfo +) -> Dict[str, Union[str, bool, float]]: + """Packs benchmarking data into a dictionary for latter serialization.""" + data_dict = { + "pipeline_cls": pipeline_cls, + "ckpt_id": ckpt, + "batch_size": args.batch_size, + "num_inference_steps": args.num_inference_steps, + "model_cpu_offload": args.model_cpu_offload, + "run_compile": args.run_compile, + "time (secs)": benchmark_info.time, + "memory (gbs)": benchmark_info.memory, + "actual_gpu_memory (gbs)": f"{(TOTAL_GPU_MEMORY):.3f}", + "github_sha": GITHUB_SHA, + } + return data_dict + + +def write_to_csv(file_name: str, data_dict: Dict[str, Union[str, bool, float]]): + """Serializes a dictionary into a CSV file.""" + with open(file_name, mode="w", newline="") as csvfile: + writer = csv.DictWriter(csvfile, fieldnames=BENCHMARK_FIELDS) + writer.writeheader() + writer.writerow(data_dict) + + +def collate_csv(input_files: List[str], output_file: str): + """Collates multiple identically structured CSVs into a single CSV file.""" + with open(output_file, mode="w", newline="") as outfile: + writer = csv.DictWriter(outfile, fieldnames=BENCHMARK_FIELDS) + writer.writeheader() + + for file in input_files: + with open(file, mode="r") as infile: + reader = csv.DictReader(infile) + for row in reader: + writer.writerow(row) diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-doc-builder/Dockerfile b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-doc-builder/Dockerfile new file mode 100644 index 0000000000000000000000000000000000000000..c9fc62707cb0dac3126c06ebc22420c1353146ff --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-doc-builder/Dockerfile @@ -0,0 +1,52 @@ +FROM ubuntu:20.04 +LABEL maintainer="Hugging Face" +LABEL repository="diffusers" + +ENV DEBIAN_FRONTEND=noninteractive + +RUN apt-get -y update \ + && apt-get install -y software-properties-common \ + && add-apt-repository ppa:deadsnakes/ppa + +RUN apt install -y bash \ + build-essential \ + git \ + git-lfs \ + curl \ + ca-certificates \ + libsndfile1-dev \ + python3.10 \ + python3-pip \ + libgl1 \ + zip \ + wget \ + python3.10-venv && \ + rm -rf /var/lib/apt/lists + +# make sure to use venv +RUN python3.10 -m venv /opt/venv +ENV PATH="/opt/venv/bin:$PATH" + +# pre-install the heavy dependencies (these can later be overridden by the deps from setup.py) +RUN python3.10 -m pip install --no-cache-dir --upgrade pip uv==0.1.11 && \ + python3.10 -m uv pip install --no-cache-dir \ + torch \ + torchvision \ + torchaudio \ + invisible_watermark \ + --extra-index-url https://download.pytorch.org/whl/cpu && \ + python3.10 -m uv pip install --no-cache-dir \ + accelerate \ + datasets \ + hf-doc-builder \ + huggingface-hub \ + Jinja2 \ + librosa \ + numpy==1.26.4 \ + scipy \ + tensorboard \ + transformers \ + matplotlib \ + setuptools==69.5.1 + +CMD ["/bin/bash"] diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-flax-cpu/Dockerfile b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-flax-cpu/Dockerfile new file mode 100644 index 0000000000000000000000000000000000000000..051008aa9a2ee057a56bfe55b7af34595c26c413 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-flax-cpu/Dockerfile @@ -0,0 +1,49 @@ +FROM ubuntu:20.04 +LABEL maintainer="Hugging Face" +LABEL repository="diffusers" + +ENV DEBIAN_FRONTEND=noninteractive + +RUN apt-get -y update \ + && apt-get install -y software-properties-common \ + && add-apt-repository ppa:deadsnakes/ppa + +RUN apt install -y bash \ + build-essential \ + git \ + git-lfs \ + curl \ + ca-certificates \ + libsndfile1-dev \ + libgl1 \ + python3.10 \ + python3-pip \ + python3.10-venv && \ + rm -rf /var/lib/apt/lists + +# make sure to use venv +RUN python3.10 -m venv /opt/venv +ENV PATH="/opt/venv/bin:$PATH" + +# pre-install the heavy dependencies (these can later be overridden by the deps from setup.py) +# follow the instructions here: https://cloud.google.com/tpu/docs/run-in-container#train_a_jax_model_in_a_docker_container +RUN python3 -m pip install --no-cache-dir --upgrade pip uv==0.1.11 && \ + python3 -m uv pip install --upgrade --no-cache-dir \ + clu \ + "jax[cpu]>=0.2.16,!=0.3.2" \ + "flax>=0.4.1" \ + "jaxlib>=0.1.65" && \ + python3 -m uv pip install --no-cache-dir \ + accelerate \ + datasets \ + hf-doc-builder \ + huggingface-hub \ + Jinja2 \ + librosa \ + numpy==1.26.4 \ + scipy \ + tensorboard \ + transformers \ + hf_transfer + +CMD ["/bin/bash"] \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-flax-tpu/Dockerfile b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-flax-tpu/Dockerfile new file mode 100644 index 0000000000000000000000000000000000000000..405f068923b79136197daa8089340734d1435c60 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-flax-tpu/Dockerfile @@ -0,0 +1,51 @@ +FROM ubuntu:20.04 +LABEL maintainer="Hugging Face" +LABEL repository="diffusers" + +ENV DEBIAN_FRONTEND=noninteractive + +RUN apt-get -y update \ + && apt-get install -y software-properties-common \ + && add-apt-repository ppa:deadsnakes/ppa + +RUN apt install -y bash \ + build-essential \ + git \ + git-lfs \ + curl \ + ca-certificates \ + libsndfile1-dev \ + libgl1 \ + python3.10 \ + python3-pip \ + python3.10-venv && \ + rm -rf /var/lib/apt/lists + +# make sure to use venv +RUN python3.10 -m venv /opt/venv +ENV PATH="/opt/venv/bin:$PATH" + +# pre-install the heavy dependencies (these can later be overridden by the deps from setup.py) +# follow the instructions here: https://cloud.google.com/tpu/docs/run-in-container#train_a_jax_model_in_a_docker_container +RUN python3 -m pip install --no-cache-dir --upgrade pip uv==0.1.11 && \ + python3 -m pip install --no-cache-dir \ + "jax[tpu]>=0.2.16,!=0.3.2" \ + -f https://storage.googleapis.com/jax-releases/libtpu_releases.html && \ + python3 -m uv pip install --upgrade --no-cache-dir \ + clu \ + "flax>=0.4.1" \ + "jaxlib>=0.1.65" && \ + python3 -m uv pip install --no-cache-dir \ + accelerate \ + datasets \ + hf-doc-builder \ + huggingface-hub \ + Jinja2 \ + librosa \ + numpy==1.26.4 \ + scipy \ + tensorboard \ + transformers \ + hf_transfer + +CMD ["/bin/bash"] \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-onnxruntime-cpu/Dockerfile b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-onnxruntime-cpu/Dockerfile new file mode 100644 index 0000000000000000000000000000000000000000..20197937cbbe6cf12bf24ecb32959f5db9f2f577 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-onnxruntime-cpu/Dockerfile @@ -0,0 +1,49 @@ +FROM ubuntu:20.04 +LABEL maintainer="Hugging Face" +LABEL repository="diffusers" + +ENV DEBIAN_FRONTEND=noninteractive + +RUN apt-get -y update \ + && apt-get install -y software-properties-common \ + && add-apt-repository ppa:deadsnakes/ppa + +RUN apt install -y bash \ + build-essential \ + git \ + git-lfs \ + curl \ + ca-certificates \ + libsndfile1-dev \ + libgl1 \ + python3.10 \ + python3-pip \ + python3.10-venv && \ + rm -rf /var/lib/apt/lists + +# make sure to use venv +RUN python3.10 -m venv /opt/venv +ENV PATH="/opt/venv/bin:$PATH" + +# pre-install the heavy dependencies (these can later be overridden by the deps from setup.py) +RUN python3 -m pip install --no-cache-dir --upgrade pip uv==0.1.11 && \ + python3 -m uv pip install --no-cache-dir \ + torch \ + torchvision \ + torchaudio\ + onnxruntime \ + --extra-index-url https://download.pytorch.org/whl/cpu && \ + python3 -m uv pip install --no-cache-dir \ + accelerate \ + datasets \ + hf-doc-builder \ + huggingface-hub \ + Jinja2 \ + librosa \ + numpy==1.26.4 \ + scipy \ + tensorboard \ + transformers \ + hf_transfer + +CMD ["/bin/bash"] \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-onnxruntime-cuda/Dockerfile b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-onnxruntime-cuda/Dockerfile new file mode 100644 index 0000000000000000000000000000000000000000..bd1d871033c96bd9eb0aa6157747c0fad3fa9093 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-onnxruntime-cuda/Dockerfile @@ -0,0 +1,50 @@ +FROM nvidia/cuda:12.1.0-runtime-ubuntu20.04 +LABEL maintainer="Hugging Face" +LABEL repository="diffusers" + +ENV DEBIAN_FRONTEND=noninteractive + +RUN apt-get -y update \ + && apt-get install -y software-properties-common \ + && add-apt-repository ppa:deadsnakes/ppa + +RUN apt install -y bash \ + build-essential \ + git \ + git-lfs \ + curl \ + ca-certificates \ + libsndfile1-dev \ + libgl1 \ + python3.10 \ + python3-pip \ + python3.10-venv && \ + rm -rf /var/lib/apt/lists + +# make sure to use venv +RUN python3.10 -m venv /opt/venv +ENV PATH="/opt/venv/bin:$PATH" + +# pre-install the heavy dependencies (these can later be overridden by the deps from setup.py) +RUN python3.10 -m pip install --no-cache-dir --upgrade pip uv==0.1.11 && \ + python3.10 -m uv pip install --no-cache-dir \ + torch \ + torchvision \ + torchaudio \ + "onnxruntime-gpu>=1.13.1" \ + --extra-index-url https://download.pytorch.org/whl/cu117 && \ + python3.10 -m uv pip install --no-cache-dir \ + accelerate \ + datasets \ + hf-doc-builder \ + huggingface-hub \ + hf_transfer \ + Jinja2 \ + librosa \ + numpy==1.26.4 \ + scipy \ + tensorboard \ + transformers \ + hf_transfer + +CMD ["/bin/bash"] \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-pytorch-cpu/Dockerfile b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-pytorch-cpu/Dockerfile new file mode 100644 index 0000000000000000000000000000000000000000..8d98c52598d2095a2842f97a2f68c56391e24431 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-pytorch-cpu/Dockerfile @@ -0,0 +1,50 @@ +FROM ubuntu:20.04 +LABEL maintainer="Hugging Face" +LABEL repository="diffusers" + +ENV DEBIAN_FRONTEND=noninteractive + +RUN apt-get -y update \ + && apt-get install -y software-properties-common \ + && add-apt-repository ppa:deadsnakes/ppa + +RUN apt install -y bash \ + build-essential \ + git \ + git-lfs \ + curl \ + ca-certificates \ + libsndfile1-dev \ + python3.10 \ + python3.10-dev \ + python3-pip \ + libgl1 \ + python3.10-venv && \ + rm -rf /var/lib/apt/lists + +# make sure to use venv +RUN python3.10 -m venv /opt/venv +ENV PATH="/opt/venv/bin:$PATH" + +# pre-install the heavy dependencies (these can later be overridden by the deps from setup.py) +RUN python3.10 -m pip install --no-cache-dir --upgrade pip uv==0.1.11 && \ + python3.10 -m uv pip install --no-cache-dir \ + torch \ + torchvision \ + torchaudio \ + invisible_watermark \ + --extra-index-url https://download.pytorch.org/whl/cpu && \ + python3.10 -m uv pip install --no-cache-dir \ + accelerate \ + datasets \ + hf-doc-builder \ + huggingface-hub \ + Jinja2 \ + librosa \ + numpy==1.26.4 \ + scipy \ + tensorboard \ + transformers matplotlib \ + hf_transfer + +CMD ["/bin/bash"] diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-pytorch-cuda/Dockerfile b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-pytorch-cuda/Dockerfile new file mode 100644 index 0000000000000000000000000000000000000000..695f5ed08dc5b202b84f57f3bfab7fe8559c9d97 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-pytorch-cuda/Dockerfile @@ -0,0 +1,51 @@ +FROM nvidia/cuda:12.1.0-runtime-ubuntu20.04 +LABEL maintainer="Hugging Face" +LABEL repository="diffusers" + +ENV DEBIAN_FRONTEND=noninteractive + +RUN apt-get -y update \ + && apt-get install -y software-properties-common \ + && add-apt-repository ppa:deadsnakes/ppa + +RUN apt install -y bash \ + build-essential \ + git \ + git-lfs \ + curl \ + ca-certificates \ + libsndfile1-dev \ + libgl1 \ + python3.10 \ + python3.10-dev \ + python3-pip \ + python3.10-venv && \ + rm -rf /var/lib/apt/lists + +# make sure to use venv +RUN python3.10 -m venv /opt/venv +ENV PATH="/opt/venv/bin:$PATH" + +# pre-install the heavy dependencies (these can later be overridden by the deps from setup.py) +RUN python3.10 -m pip install --no-cache-dir --upgrade pip uv==0.1.11 && \ + python3.10 -m uv pip install --no-cache-dir \ + torch \ + torchvision \ + torchaudio \ + invisible_watermark && \ + python3.10 -m pip install --no-cache-dir \ + accelerate \ + datasets \ + hf-doc-builder \ + huggingface-hub \ + hf_transfer \ + Jinja2 \ + librosa \ + numpy==1.26.4 \ + scipy \ + tensorboard \ + transformers \ + pytorch-lightning \ + hf_transfer + +CMD ["/bin/bash"] diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-pytorch-minimum-cuda/Dockerfile b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-pytorch-minimum-cuda/Dockerfile new file mode 100644 index 0000000000000000000000000000000000000000..57ca7657acf139a0baabd0b087e19f02986dd07b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-pytorch-minimum-cuda/Dockerfile @@ -0,0 +1,53 @@ +FROM nvidia/cuda:12.1.0-runtime-ubuntu20.04 +LABEL maintainer="Hugging Face" +LABEL repository="diffusers" + +ENV DEBIAN_FRONTEND=noninteractive +ENV MINIMUM_SUPPORTED_TORCH_VERSION="2.1.0" +ENV MINIMUM_SUPPORTED_TORCHVISION_VERSION="0.16.0" +ENV MINIMUM_SUPPORTED_TORCHAUDIO_VERSION="2.1.0" + +RUN apt-get -y update \ + && apt-get install -y software-properties-common \ + && add-apt-repository ppa:deadsnakes/ppa + +RUN apt install -y bash \ + build-essential \ + git \ + git-lfs \ + curl \ + ca-certificates \ + libsndfile1-dev \ + libgl1 \ + python3.10 \ + python3.10-dev \ + python3-pip \ + python3.10-venv && \ + rm -rf /var/lib/apt/lists + +# make sure to use venv +RUN python3.10 -m venv /opt/venv +ENV PATH="/opt/venv/bin:$PATH" + +# pre-install the heavy dependencies (these can later be overridden by the deps from setup.py) +RUN python3.10 -m pip install --no-cache-dir --upgrade pip uv==0.1.11 && \ + python3.10 -m uv pip install --no-cache-dir \ + torch==$MINIMUM_SUPPORTED_TORCH_VERSION \ + torchvision==$MINIMUM_SUPPORTED_TORCHVISION_VERSION \ + torchaudio==$MINIMUM_SUPPORTED_TORCHAUDIO_VERSION \ + invisible_watermark && \ + python3.10 -m pip install --no-cache-dir \ + accelerate \ + datasets \ + hf-doc-builder \ + huggingface-hub \ + hf_transfer \ + Jinja2 \ + librosa \ + numpy==1.26.4 \ + scipy \ + tensorboard \ + transformers \ + hf_transfer + +CMD ["/bin/bash"] diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-pytorch-xformers-cuda/Dockerfile b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-pytorch-xformers-cuda/Dockerfile new file mode 100644 index 0000000000000000000000000000000000000000..1693eb2930242d950f591aa461e7d527c7268fc6 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docker/diffusers-pytorch-xformers-cuda/Dockerfile @@ -0,0 +1,51 @@ +FROM nvidia/cuda:12.1.0-runtime-ubuntu20.04 +LABEL maintainer="Hugging Face" +LABEL repository="diffusers" + +ENV DEBIAN_FRONTEND=noninteractive + +RUN apt-get -y update \ + && apt-get install -y software-properties-common \ + && add-apt-repository ppa:deadsnakes/ppa + +RUN apt install -y bash \ + build-essential \ + git \ + git-lfs \ + curl \ + ca-certificates \ + libsndfile1-dev \ + libgl1 \ + python3.10 \ + python3.10-dev \ + python3-pip \ + python3.10-venv && \ + rm -rf /var/lib/apt/lists + +# make sure to use venv +RUN python3.10 -m venv /opt/venv +ENV PATH="/opt/venv/bin:$PATH" + +# pre-install the heavy dependencies (these can later be overridden by the deps from setup.py) +RUN python3.10 -m pip install --no-cache-dir --upgrade pip uv==0.1.11 && \ + python3.10 -m pip install --no-cache-dir \ + torch \ + torchvision \ + torchaudio \ + invisible_watermark && \ + python3.10 -m uv pip install --no-cache-dir \ + accelerate \ + datasets \ + hf-doc-builder \ + huggingface-hub \ + hf_transfer \ + Jinja2 \ + librosa \ + numpy==1.26.4 \ + scipy \ + tensorboard \ + transformers \ + xformers \ + hf_transfer + +CMD ["/bin/bash"] diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/README.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/README.md new file mode 100644 index 0000000000000000000000000000000000000000..f36b76fb07891cc556db8ac30633abcea01c4a41 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/README.md @@ -0,0 +1,268 @@ + + +# Generating the documentation + +To generate the documentation, you first have to build it. Several packages are necessary to build the doc, +you can install them with the following command, at the root of the code repository: + +```bash +pip install -e ".[docs]" +``` + +Then you need to install our open source documentation builder tool: + +```bash +pip install git+https://github.com/huggingface/doc-builder +``` + +--- +**NOTE** + +You only need to generate the documentation to inspect it locally (if you're planning changes and want to +check how they look before committing for instance). You don't have to commit the built documentation. + +--- + +## Previewing the documentation + +To preview the docs, first install the `watchdog` module with: + +```bash +pip install watchdog +``` + +Then run the following command: + +```bash +doc-builder preview {package_name} {path_to_docs} +``` + +For example: + +```bash +doc-builder preview diffusers docs/source/en +``` + +The docs will be viewable at [http://localhost:3000](http://localhost:3000). You can also preview the docs once you have opened a PR. You will see a bot add a comment to a link where the documentation with your changes lives. + +--- +**NOTE** + +The `preview` command only works with existing doc files. When you add a completely new file, you need to update `_toctree.yml` & restart `preview` command (`ctrl-c` to stop it & call `doc-builder preview ...` again). + +--- + +## Adding a new element to the navigation bar + +Accepted files are Markdown (.md). + +Create a file with its extension and put it in the source directory. You can then link it to the toc-tree by putting +the filename without the extension in the [`_toctree.yml`](https://github.com/huggingface/diffusers/blob/main/docs/source/en/_toctree.yml) file. + +## Renaming section headers and moving sections + +It helps to keep the old links working when renaming the section header and/or moving sections from one document to another. This is because the old links are likely to be used in Issues, Forums, and Social media and it'd make for a much more superior user experience if users reading those months later could still easily navigate to the originally intended information. + +Therefore, we simply keep a little map of moved sections at the end of the document where the original section was. The key is to preserve the original anchor. + +So if you renamed a section from: "Section A" to "Section B", then you can add at the end of the file: + +```md +Sections that were moved: + +[ Section A ] +``` +and of course, if you moved it to another file, then: + +```md +Sections that were moved: + +[ Section A ] +``` + +Use the relative style to link to the new file so that the versioned docs continue to work. + +For an example of a rich moved section set please see the very end of [the transformers Trainer doc](https://github.com/huggingface/transformers/blob/main/docs/source/en/main_classes/trainer.md). + + +## Writing Documentation - Specification + +The `huggingface/diffusers` documentation follows the +[Google documentation](https://sphinxcontrib-napoleon.readthedocs.io/en/latest/example_google.html) style for docstrings, +although we can write them directly in Markdown. + +### Adding a new tutorial + +Adding a new tutorial or section is done in two steps: + +- Add a new Markdown (.md) file under `docs/source/`. +- Link that file in `docs/source//_toctree.yml` on the correct toc-tree. + +Make sure to put your new file under the proper section. It's unlikely to go in the first section (*Get Started*), so +depending on the intended targets (beginners, more advanced users, or researchers) it should go in sections two, three, or four. + +### Adding a new pipeline/scheduler + +When adding a new pipeline: + +- Create a file `xxx.md` under `docs/source//api/pipelines` (don't hesitate to copy an existing file as template). +- Link that file in (*Diffusers Summary*) section in `docs/source/api/pipelines/overview.md`, along with the link to the paper, and a colab notebook (if available). +- Write a short overview of the diffusion model: + - Overview with paper & authors + - Paper abstract + - Tips and tricks and how to use it best + - Possible an end-to-end example of how to use it +- Add all the pipeline classes that should be linked in the diffusion model. These classes should be added using our Markdown syntax. By default as follows: + +``` +[[autodoc]] XXXPipeline + - all + - __call__ +``` + +This will include every public method of the pipeline that is documented, as well as the `__call__` method that is not documented by default. If you just want to add additional methods that are not documented, you can put the list of all methods to add in a list that contains `all`. + +``` +[[autodoc]] XXXPipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention +``` + +You can follow the same process to create a new scheduler under the `docs/source//api/schedulers` folder. + +### Writing source documentation + +Values that should be put in `code` should either be surrounded by backticks: \`like so\`. Note that argument names +and objects like True, None, or any strings should usually be put in `code`. + +When mentioning a class, function, or method, it is recommended to use our syntax for internal links so that our tool +adds a link to its documentation with this syntax: \[\`XXXClass\`\] or \[\`function\`\]. This requires the class or +function to be in the main package. + +If you want to create a link to some internal class or function, you need to +provide its path. For instance: \[\`pipelines.ImagePipelineOutput\`\]. This will be converted into a link with +`pipelines.ImagePipelineOutput` in the description. To get rid of the path and only keep the name of the object you are +linking to in the description, add a ~: \[\`~pipelines.ImagePipelineOutput\`\] will generate a link with `ImagePipelineOutput` in the description. + +The same works for methods so you can either use \[\`XXXClass.method\`\] or \[\`~XXXClass.method\`\]. + +#### Defining arguments in a method + +Arguments should be defined with the `Args:` (or `Arguments:` or `Parameters:`) prefix, followed by a line return and +an indentation. The argument should be followed by its type, with its shape if it is a tensor, a colon, and its +description: + +``` + Args: + n_layers (`int`): The number of layers of the model. +``` + +If the description is too long to fit in one line, another indentation is necessary before writing the description +after the argument. + +Here's an example showcasing everything so far: + +``` + Args: + input_ids (`torch.LongTensor` of shape `(batch_size, sequence_length)`): + Indices of input sequence tokens in the vocabulary. + + Indices can be obtained using [`AlbertTokenizer`]. See [`~PreTrainedTokenizer.encode`] and + [`~PreTrainedTokenizer.__call__`] for details. + + [What are input IDs?](../glossary#input-ids) +``` + +For optional arguments or arguments with defaults we follow the following syntax: imagine we have a function with the +following signature: + +```py +def my_function(x: str=None, a: float=3.14): +``` + +then its documentation should look like this: + +``` + Args: + x (`str`, *optional*): + This argument controls ... + a (`float`, *optional*, defaults to `3.14`): + This argument is used to ... +``` + +Note that we always omit the "defaults to \`None\`" when None is the default for any argument. Also note that even +if the first line describing your argument type and its default gets long, you can't break it on several lines. You can +however write as many lines as you want in the indented description (see the example above with `input_ids`). + +#### Writing a multi-line code block + +Multi-line code blocks can be useful for displaying examples. They are done between two lines of three backticks as usual in Markdown: + + +```` +``` +# first line of code +# second line +# etc +``` +```` + +#### Writing a return block + +The return block should be introduced with the `Returns:` prefix, followed by a line return and an indentation. +The first line should be the type of the return, followed by a line return. No need to indent further for the elements +building the return. + +Here's an example of a single value return: + +``` + Returns: + `List[int]`: A list of integers in the range [0, 1] --- 1 for a special token, 0 for a sequence token. +``` + +Here's an example of a tuple return, comprising several objects: + +``` + Returns: + `tuple(torch.Tensor)` comprising various elements depending on the configuration ([`BertConfig`]) and inputs: + - ** loss** (*optional*, returned when `masked_lm_labels` is provided) `torch.Tensor` of shape `(1,)` -- + Total loss is the sum of the masked language modeling loss and the next sequence prediction (classification) loss. + - **prediction_scores** (`torch.Tensor` of shape `(batch_size, sequence_length, config.vocab_size)`) -- + Prediction scores of the language modeling head (scores for each vocabulary token before SoftMax). +``` + +#### Adding an image + +Due to the rapidly growing repository, it is important to make sure that no files that would significantly weigh down the repository are added. This includes images, videos, and other non-text files. We prefer to leverage a hf.co hosted `dataset` like +the ones hosted on [`hf-internal-testing`](https://huggingface.co/hf-internal-testing) in which to place these files and reference +them by URL. We recommend putting them in the following dataset: [huggingface/documentation-images](https://huggingface.co/datasets/huggingface/documentation-images). +If an external contribution, feel free to add the images to your PR and ask a Hugging Face member to migrate your images +to this dataset. + +## Styling the docstring + +We have an automatic script running with the `make style` command that will make sure that: +- the docstrings fully take advantage of the line width +- all code examples are formatted using black, like the code of the Transformers library + +This script may have some weird failures if you made a syntax mistake or if you uncover a bug. Therefore, it's +recommended to commit your changes before running `make style`, so you can revert the changes done by that script +easily. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/TRANSLATING.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/TRANSLATING.md new file mode 100644 index 0000000000000000000000000000000000000000..f88bec8595c87cc329fea49c922ccdf592d2a3bb --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/TRANSLATING.md @@ -0,0 +1,69 @@ + + +### Translating the Diffusers documentation into your language + +As part of our mission to democratize machine learning, we'd love to make the Diffusers library available in many more languages! Follow the steps below if you want to help translate the documentation into your language 🙏. + +**🗞️ Open an issue** + +To get started, navigate to the [Issues](https://github.com/huggingface/diffusers/issues) page of this repo and check if anyone else has opened an issue for your language. If not, open a new issue by selecting the "🌐 Translating a New Language?" from the "New issue" button. + +Once an issue exists, post a comment to indicate which chapters you'd like to work on, and we'll add your name to the list. + + +**🍴 Fork the repository** + +First, you'll need to [fork the Diffusers repo](https://docs.github.com/en/get-started/quickstart/fork-a-repo). You can do this by clicking on the **Fork** button on the top-right corner of this repo's page. + +Once you've forked the repo, you'll want to get the files on your local machine for editing. You can do that by cloning the fork with Git as follows: + +```bash +git clone https://github.com//diffusers.git +``` + +**📋 Copy-paste the English version with a new language code** + +The documentation files are in one leading directory: + +- [`docs/source`](https://github.com/huggingface/diffusers/tree/main/docs/source): All the documentation materials are organized here by language. + +You'll only need to copy the files in the [`docs/source/en`](https://github.com/huggingface/diffusers/tree/main/docs/source/en) directory, so first navigate to your fork of the repo and run the following: + +```bash +cd ~/path/to/diffusers/docs +cp -r source/en source/ +``` + +Here, `` should be one of the ISO 639-1 or ISO 639-2 language codes -- see [here](https://www.loc.gov/standards/iso639-2/php/code_list.php) for a handy table. + +**✍️ Start translating** + +The fun part comes - translating the text! + +The first thing we recommend is translating the part of the `_toctree.yml` file that corresponds to your doc chapter. This file is used to render the table of contents on the website. + +> 🙋 If the `_toctree.yml` file doesn't yet exist for your language, you can create one by copy-pasting from the English version and deleting the sections unrelated to your chapter. Just make sure it exists in the `docs/source//` directory! + +The fields you should add are `local` (with the name of the file containing the translation; e.g. `autoclass_tutorial`), and `title` (with the title of the doc in your language; e.g. `Load pretrained instances with an AutoClass`) -- as a reference, here is the `_toctree.yml` for [English](https://github.com/huggingface/diffusers/blob/main/docs/source/en/_toctree.yml): + +```yaml +- sections: + - local: pipeline_tutorial # Do not change this! Use the same name for your .md file + title: Pipelines for inference # Translate this! + ... + title: Tutorials # Translate this! +``` + +Once you have translated the `_toctree.yml` file, you can start translating the [MDX](https://mdxjs.com/) files associated with your docs chapter. + +> 🙋 If you'd like others to help you with the translation, you should [open an issue](https://github.com/huggingface/diffusers/issues) and tag @patrickvonplaten. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/_config.py b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/_config.py new file mode 100644 index 0000000000000000000000000000000000000000..3d0d73dcb951ea5b8b91e255d79b893a2a103ed3 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/_config.py @@ -0,0 +1,9 @@ +# docstyle-ignore +INSTALL_CONTENT = """ +# Diffusers installation +! pip install diffusers transformers datasets accelerate +# To install from source instead of the last release, comment the command above and uncomment the following one. +# ! pip install git+https://github.com/huggingface/diffusers.git +""" + +notebook_first_cells = [{"type": "code", "content": INSTALL_CONTENT}] diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/_toctree.yml b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/_toctree.yml new file mode 100644 index 0000000000000000000000000000000000000000..401a40d645dab960945a0b5b1a63389a0632d9ba --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/_toctree.yml @@ -0,0 +1,673 @@ +- sections: + - local: index + title: 🧨 Diffusers + - local: quicktour + title: Quicktour + - local: stable_diffusion + title: Effective and efficient diffusion + - local: installation + title: Installation + title: Get started +- sections: + - local: tutorials/tutorial_overview + title: Overview + - local: using-diffusers/write_own_pipeline + title: Understanding pipelines, models and schedulers + - local: tutorials/autopipeline + title: AutoPipeline + - local: tutorials/basic_training + title: Train a diffusion model + title: Tutorials +- sections: + - local: using-diffusers/loading + title: Load pipelines + - local: using-diffusers/custom_pipeline_overview + title: Load community pipelines and components + - local: using-diffusers/schedulers + title: Load schedulers and models + - local: using-diffusers/other-formats + title: Model files and layouts + - local: using-diffusers/push_to_hub + title: Push files to the Hub + title: Load pipelines and adapters +- sections: + - local: tutorials/using_peft_for_inference + title: LoRA + - local: using-diffusers/ip_adapter + title: IP-Adapter + - local: using-diffusers/controlnet + title: ControlNet + - local: using-diffusers/t2i_adapter + title: T2I-Adapter + - local: using-diffusers/dreambooth + title: DreamBooth + - local: using-diffusers/textual_inversion_inference + title: Textual inversion + title: Adapters + isExpanded: false +- sections: + - local: using-diffusers/unconditional_image_generation + title: Unconditional image generation + - local: using-diffusers/conditional_image_generation + title: Text-to-image + - local: using-diffusers/img2img + title: Image-to-image + - local: using-diffusers/inpaint + title: Inpainting + - local: using-diffusers/text-img2vid + title: Video generation + - local: using-diffusers/depth2img + title: Depth-to-image + title: Generative tasks +- sections: + - local: using-diffusers/overview_techniques + title: Overview + - local: using-diffusers/create_a_server + title: Create a server + - local: training/distributed_inference + title: Distributed inference + - local: using-diffusers/scheduler_features + title: Scheduler features + - local: using-diffusers/callback + title: Pipeline callbacks + - local: using-diffusers/reusing_seeds + title: Reproducible pipelines + - local: using-diffusers/image_quality + title: Controlling image quality + - local: using-diffusers/weighted_prompts + title: Prompt techniques + title: Inference techniques +- sections: + - local: advanced_inference/outpaint + title: Outpainting + title: Advanced inference +- sections: + - local: hybrid_inference/overview + title: Overview + - local: hybrid_inference/vae_decode + title: VAE Decode + - local: hybrid_inference/vae_encode + title: VAE Encode + - local: hybrid_inference/api_reference + title: API Reference + title: Hybrid Inference +- sections: + - local: using-diffusers/cogvideox + title: CogVideoX + - local: using-diffusers/consisid + title: ConsisID + - local: using-diffusers/sdxl + title: Stable Diffusion XL + - local: using-diffusers/sdxl_turbo + title: SDXL Turbo + - local: using-diffusers/kandinsky + title: Kandinsky + - local: using-diffusers/omnigen + title: OmniGen + - local: using-diffusers/pag + title: PAG + - local: using-diffusers/inference_with_lcm + title: Latent Consistency Model + - local: using-diffusers/shap-e + title: Shap-E + - local: using-diffusers/diffedit + title: DiffEdit + - local: using-diffusers/inference_with_tcd_lora + title: Trajectory Consistency Distillation-LoRA + - local: using-diffusers/svd + title: Stable Video Diffusion + - local: using-diffusers/marigold_usage + title: Marigold Computer Vision + title: Specific pipeline examples +- sections: + - local: training/overview + title: Overview + - local: training/create_dataset + title: Create a dataset for training + - local: training/adapt_a_model + title: Adapt a model to a new task + - isExpanded: false + sections: + - local: training/unconditional_training + title: Unconditional image generation + - local: training/text2image + title: Text-to-image + - local: training/sdxl + title: Stable Diffusion XL + - local: training/kandinsky + title: Kandinsky 2.2 + - local: training/wuerstchen + title: Wuerstchen + - local: training/controlnet + title: ControlNet + - local: training/t2i_adapters + title: T2I-Adapters + - local: training/instructpix2pix + title: InstructPix2Pix + - local: training/cogvideox + title: CogVideoX + title: Models + - isExpanded: false + sections: + - local: training/text_inversion + title: Textual Inversion + - local: training/dreambooth + title: DreamBooth + - local: training/lora + title: LoRA + - local: training/custom_diffusion + title: Custom Diffusion + - local: training/lcm_distill + title: Latent Consistency Distillation + - local: training/ddpo + title: Reinforcement learning training with DDPO + title: Methods + title: Training +- sections: + - local: quantization/overview + title: Getting Started + - local: quantization/bitsandbytes + title: bitsandbytes + - local: quantization/gguf + title: gguf + - local: quantization/torchao + title: torchao + - local: quantization/quanto + title: quanto + title: Quantization Methods +- sections: + - local: optimization/fp16 + title: Accelerate inference + - local: optimization/memory + title: Reduce memory usage + - local: optimization/torch2.0 + title: PyTorch 2.0 + - local: optimization/xformers + title: xFormers + - local: optimization/tome + title: Token merging + - local: optimization/deepcache + title: DeepCache + - local: optimization/tgate + title: TGATE + - local: optimization/xdit + title: xDiT + - local: optimization/para_attn + title: ParaAttention + - sections: + - local: using-diffusers/stable_diffusion_jax_how_to + title: JAX/Flax + - local: optimization/onnx + title: ONNX + - local: optimization/open_vino + title: OpenVINO + - local: optimization/coreml + title: Core ML + title: Optimized model formats + - sections: + - local: optimization/mps + title: Metal Performance Shaders (MPS) + - local: optimization/habana + title: Intel Gaudi + - local: optimization/neuron + title: AWS Neuron + title: Optimized hardware + title: Accelerate inference and reduce memory +- sections: + - local: conceptual/philosophy + title: Philosophy + - local: using-diffusers/controlling_generation + title: Controlled generation + - local: conceptual/contribution + title: How to contribute? + - local: conceptual/ethical_guidelines + title: Diffusers' Ethical Guidelines + - local: conceptual/evaluation + title: Evaluating Diffusion Models + title: Conceptual Guides +- sections: + - local: community_projects + title: Projects built with Diffusers + title: Community Projects +- sections: + - isExpanded: false + sections: + - local: api/configuration + title: Configuration + - local: api/logging + title: Logging + - local: api/outputs + title: Outputs + - local: api/quantization + title: Quantization + title: Main Classes + - isExpanded: false + sections: + - local: api/loaders/ip_adapter + title: IP-Adapter + - local: api/loaders/lora + title: LoRA + - local: api/loaders/single_file + title: Single files + - local: api/loaders/textual_inversion + title: Textual Inversion + - local: api/loaders/unet + title: UNet + - local: api/loaders/transformer_sd3 + title: SD3Transformer2D + - local: api/loaders/peft + title: PEFT + title: Loaders + - isExpanded: false + sections: + - local: api/models/overview + title: Overview + - local: api/models/auto_model + title: AutoModel + - sections: + - local: api/models/controlnet + title: ControlNetModel + - local: api/models/controlnet_union + title: ControlNetUnionModel + - local: api/models/controlnet_flux + title: FluxControlNetModel + - local: api/models/controlnet_hunyuandit + title: HunyuanDiT2DControlNetModel + - local: api/models/controlnet_sana + title: SanaControlNetModel + - local: api/models/controlnet_sd3 + title: SD3ControlNetModel + - local: api/models/controlnet_sparsectrl + title: SparseControlNetModel + title: ControlNets + - sections: + - local: api/models/allegro_transformer3d + title: AllegroTransformer3DModel + - local: api/models/aura_flow_transformer2d + title: AuraFlowTransformer2DModel + - local: api/models/cogvideox_transformer3d + title: CogVideoXTransformer3DModel + - local: api/models/cogview3plus_transformer2d + title: CogView3PlusTransformer2DModel + - local: api/models/cogview4_transformer2d + title: CogView4Transformer2DModel + - local: api/models/consisid_transformer3d + title: ConsisIDTransformer3DModel + - local: api/models/cosmos_transformer3d + title: CosmosTransformer3DModel + - local: api/models/dit_transformer2d + title: DiTTransformer2DModel + - local: api/models/easyanimate_transformer3d + title: EasyAnimateTransformer3DModel + - local: api/models/flux_transformer + title: FluxTransformer2DModel + - local: api/models/hidream_image_transformer + title: HiDreamImageTransformer2DModel + - local: api/models/hunyuan_transformer2d + title: HunyuanDiT2DModel + - local: api/models/hunyuan_video_transformer_3d + title: HunyuanVideoTransformer3DModel + - local: api/models/latte_transformer3d + title: LatteTransformer3DModel + - local: api/models/ltx_video_transformer3d + title: LTXVideoTransformer3DModel + - local: api/models/lumina2_transformer2d + title: Lumina2Transformer2DModel + - local: api/models/lumina_nextdit2d + title: LuminaNextDiT2DModel + - local: api/models/mochi_transformer3d + title: MochiTransformer3DModel + - local: api/models/omnigen_transformer + title: OmniGenTransformer2DModel + - local: api/models/pixart_transformer2d + title: PixArtTransformer2DModel + - local: api/models/prior_transformer + title: PriorTransformer + - local: api/models/sana_transformer2d + title: SanaTransformer2DModel + - local: api/models/sd3_transformer2d + title: SD3Transformer2DModel + - local: api/models/stable_audio_transformer + title: StableAudioDiTModel + - local: api/models/transformer2d + title: Transformer2DModel + - local: api/models/transformer_temporal + title: TransformerTemporalModel + - local: api/models/wan_transformer_3d + title: WanTransformer3DModel + title: Transformers + - sections: + - local: api/models/stable_cascade_unet + title: StableCascadeUNet + - local: api/models/unet + title: UNet1DModel + - local: api/models/unet2d-cond + title: UNet2DConditionModel + - local: api/models/unet2d + title: UNet2DModel + - local: api/models/unet3d-cond + title: UNet3DConditionModel + - local: api/models/unet-motion + title: UNetMotionModel + - local: api/models/uvit2d + title: UViT2DModel + title: UNets + - sections: + - local: api/models/asymmetricautoencoderkl + title: AsymmetricAutoencoderKL + - local: api/models/autoencoder_dc + title: AutoencoderDC + - local: api/models/autoencoderkl + title: AutoencoderKL + - local: api/models/autoencoderkl_allegro + title: AutoencoderKLAllegro + - local: api/models/autoencoderkl_cogvideox + title: AutoencoderKLCogVideoX + - local: api/models/autoencoderkl_cosmos + title: AutoencoderKLCosmos + - local: api/models/autoencoder_kl_hunyuan_video + title: AutoencoderKLHunyuanVideo + - local: api/models/autoencoderkl_ltx_video + title: AutoencoderKLLTXVideo + - local: api/models/autoencoderkl_magvit + title: AutoencoderKLMagvit + - local: api/models/autoencoderkl_mochi + title: AutoencoderKLMochi + - local: api/models/autoencoder_kl_wan + title: AutoencoderKLWan + - local: api/models/consistency_decoder_vae + title: ConsistencyDecoderVAE + - local: api/models/autoencoder_oobleck + title: Oobleck AutoEncoder + - local: api/models/autoencoder_tiny + title: Tiny AutoEncoder + - local: api/models/vq + title: VQModel + title: VAEs + title: Models + - isExpanded: false + sections: + - local: api/pipelines/overview + title: Overview + - local: api/pipelines/allegro + title: Allegro + - local: api/pipelines/amused + title: aMUSEd + - local: api/pipelines/animatediff + title: AnimateDiff + - local: api/pipelines/attend_and_excite + title: Attend-and-Excite + - local: api/pipelines/audioldm + title: AudioLDM + - local: api/pipelines/audioldm2 + title: AudioLDM 2 + - local: api/pipelines/aura_flow + title: AuraFlow + - local: api/pipelines/auto_pipeline + title: AutoPipeline + - local: api/pipelines/blip_diffusion + title: BLIP-Diffusion + - local: api/pipelines/cogvideox + title: CogVideoX + - local: api/pipelines/cogview3 + title: CogView3 + - local: api/pipelines/cogview4 + title: CogView4 + - local: api/pipelines/consisid + title: ConsisID + - local: api/pipelines/consistency_models + title: Consistency Models + - local: api/pipelines/controlnet + title: ControlNet + - local: api/pipelines/controlnet_flux + title: ControlNet with Flux.1 + - local: api/pipelines/controlnet_hunyuandit + title: ControlNet with Hunyuan-DiT + - local: api/pipelines/controlnet_sd3 + title: ControlNet with Stable Diffusion 3 + - local: api/pipelines/controlnet_sdxl + title: ControlNet with Stable Diffusion XL + - local: api/pipelines/controlnet_sana + title: ControlNet-Sana + - local: api/pipelines/controlnetxs + title: ControlNet-XS + - local: api/pipelines/controlnetxs_sdxl + title: ControlNet-XS with Stable Diffusion XL + - local: api/pipelines/controlnet_union + title: ControlNetUnion + - local: api/pipelines/cosmos + title: Cosmos + - local: api/pipelines/dance_diffusion + title: Dance Diffusion + - local: api/pipelines/ddim + title: DDIM + - local: api/pipelines/ddpm + title: DDPM + - local: api/pipelines/deepfloyd_if + title: DeepFloyd IF + - local: api/pipelines/diffedit + title: DiffEdit + - local: api/pipelines/dit + title: DiT + - local: api/pipelines/easyanimate + title: EasyAnimate + - local: api/pipelines/flux + title: Flux + - local: api/pipelines/control_flux_inpaint + title: FluxControlInpaint + - local: api/pipelines/framepack + title: Framepack + - local: api/pipelines/hidream + title: HiDream-I1 + - local: api/pipelines/hunyuandit + title: Hunyuan-DiT + - local: api/pipelines/hunyuan_video + title: HunyuanVideo + - local: api/pipelines/i2vgenxl + title: I2VGen-XL + - local: api/pipelines/pix2pix + title: InstructPix2Pix + - local: api/pipelines/kandinsky + title: Kandinsky 2.1 + - local: api/pipelines/kandinsky_v22 + title: Kandinsky 2.2 + - local: api/pipelines/kandinsky3 + title: Kandinsky 3 + - local: api/pipelines/kolors + title: Kolors + - local: api/pipelines/latent_consistency_models + title: Latent Consistency Models + - local: api/pipelines/latent_diffusion + title: Latent Diffusion + - local: api/pipelines/latte + title: Latte + - local: api/pipelines/ledits_pp + title: LEDITS++ + - local: api/pipelines/ltx_video + title: LTXVideo + - local: api/pipelines/lumina2 + title: Lumina 2.0 + - local: api/pipelines/lumina + title: Lumina-T2X + - local: api/pipelines/marigold + title: Marigold + - local: api/pipelines/mochi + title: Mochi + - local: api/pipelines/panorama + title: MultiDiffusion + - local: api/pipelines/musicldm + title: MusicLDM + - local: api/pipelines/omnigen + title: OmniGen + - local: api/pipelines/pag + title: PAG + - local: api/pipelines/paint_by_example + title: Paint by Example + - local: api/pipelines/pia + title: Personalized Image Animator (PIA) + - local: api/pipelines/pixart + title: PixArt-α + - local: api/pipelines/pixart_sigma + title: PixArt-Σ + - local: api/pipelines/sana + title: Sana + - local: api/pipelines/sana_sprint + title: Sana Sprint + - local: api/pipelines/self_attention_guidance + title: Self-Attention Guidance + - local: api/pipelines/semantic_stable_diffusion + title: Semantic Guidance + - local: api/pipelines/shap_e + title: Shap-E + - local: api/pipelines/stable_audio + title: Stable Audio + - local: api/pipelines/stable_cascade + title: Stable Cascade + - sections: + - local: api/pipelines/stable_diffusion/overview + title: Overview + - local: api/pipelines/stable_diffusion/depth2img + title: Depth-to-image + - local: api/pipelines/stable_diffusion/gligen + title: GLIGEN (Grounded Language-to-Image Generation) + - local: api/pipelines/stable_diffusion/image_variation + title: Image variation + - local: api/pipelines/stable_diffusion/img2img + title: Image-to-image + - local: api/pipelines/stable_diffusion/svd + title: Image-to-video + - local: api/pipelines/stable_diffusion/inpaint + title: Inpainting + - local: api/pipelines/stable_diffusion/k_diffusion + title: K-Diffusion + - local: api/pipelines/stable_diffusion/latent_upscale + title: Latent upscaler + - local: api/pipelines/stable_diffusion/ldm3d_diffusion + title: LDM3D Text-to-(RGB, Depth), Text-to-(RGB-pano, Depth-pano), LDM3D Upscaler + - local: api/pipelines/stable_diffusion/stable_diffusion_safe + title: Safe Stable Diffusion + - local: api/pipelines/stable_diffusion/sdxl_turbo + title: SDXL Turbo + - local: api/pipelines/stable_diffusion/stable_diffusion_2 + title: Stable Diffusion 2 + - local: api/pipelines/stable_diffusion/stable_diffusion_3 + title: Stable Diffusion 3 + - local: api/pipelines/stable_diffusion/stable_diffusion_xl + title: Stable Diffusion XL + - local: api/pipelines/stable_diffusion/upscale + title: Super-resolution + - local: api/pipelines/stable_diffusion/adapter + title: T2I-Adapter + - local: api/pipelines/stable_diffusion/text2img + title: Text-to-image + title: Stable Diffusion + - local: api/pipelines/stable_unclip + title: Stable unCLIP + - local: api/pipelines/text_to_video + title: Text-to-video + - local: api/pipelines/text_to_video_zero + title: Text2Video-Zero + - local: api/pipelines/unclip + title: unCLIP + - local: api/pipelines/unidiffuser + title: UniDiffuser + - local: api/pipelines/value_guided_sampling + title: Value-guided sampling + - local: api/pipelines/visualcloze + title: VisualCloze + - local: api/pipelines/wan + title: Wan + - local: api/pipelines/wuerstchen + title: Wuerstchen + title: Pipelines + - isExpanded: false + sections: + - local: api/schedulers/overview + title: Overview + - local: api/schedulers/cm_stochastic_iterative + title: CMStochasticIterativeScheduler + - local: api/schedulers/ddim_cogvideox + title: CogVideoXDDIMScheduler + - local: api/schedulers/multistep_dpm_solver_cogvideox + title: CogVideoXDPMScheduler + - local: api/schedulers/consistency_decoder + title: ConsistencyDecoderScheduler + - local: api/schedulers/cosine_dpm + title: CosineDPMSolverMultistepScheduler + - local: api/schedulers/ddim_inverse + title: DDIMInverseScheduler + - local: api/schedulers/ddim + title: DDIMScheduler + - local: api/schedulers/ddpm + title: DDPMScheduler + - local: api/schedulers/deis + title: DEISMultistepScheduler + - local: api/schedulers/multistep_dpm_solver_inverse + title: DPMSolverMultistepInverse + - local: api/schedulers/multistep_dpm_solver + title: DPMSolverMultistepScheduler + - local: api/schedulers/dpm_sde + title: DPMSolverSDEScheduler + - local: api/schedulers/singlestep_dpm_solver + title: DPMSolverSinglestepScheduler + - local: api/schedulers/edm_multistep_dpm_solver + title: EDMDPMSolverMultistepScheduler + - local: api/schedulers/edm_euler + title: EDMEulerScheduler + - local: api/schedulers/euler_ancestral + title: EulerAncestralDiscreteScheduler + - local: api/schedulers/euler + title: EulerDiscreteScheduler + - local: api/schedulers/flow_match_euler_discrete + title: FlowMatchEulerDiscreteScheduler + - local: api/schedulers/flow_match_heun_discrete + title: FlowMatchHeunDiscreteScheduler + - local: api/schedulers/heun + title: HeunDiscreteScheduler + - local: api/schedulers/ipndm + title: IPNDMScheduler + - local: api/schedulers/stochastic_karras_ve + title: KarrasVeScheduler + - local: api/schedulers/dpm_discrete_ancestral + title: KDPM2AncestralDiscreteScheduler + - local: api/schedulers/dpm_discrete + title: KDPM2DiscreteScheduler + - local: api/schedulers/lcm + title: LCMScheduler + - local: api/schedulers/lms_discrete + title: LMSDiscreteScheduler + - local: api/schedulers/pndm + title: PNDMScheduler + - local: api/schedulers/repaint + title: RePaintScheduler + - local: api/schedulers/score_sde_ve + title: ScoreSdeVeScheduler + - local: api/schedulers/score_sde_vp + title: ScoreSdeVpScheduler + - local: api/schedulers/tcd + title: TCDScheduler + - local: api/schedulers/unipc + title: UniPCMultistepScheduler + - local: api/schedulers/vq_diffusion + title: VQDiffusionScheduler + title: Schedulers + - isExpanded: false + sections: + - local: api/internal_classes_overview + title: Overview + - local: api/attnprocessor + title: Attention Processor + - local: api/activations + title: Custom activation functions + - local: api/cache + title: Caching methods + - local: api/normalization + title: Custom normalization layers + - local: api/utilities + title: Utilities + - local: api/image_processor + title: VAE Image Processor + - local: api/video_processor + title: Video Processor + title: Internal classes + title: API diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/advanced_inference/outpaint.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/advanced_inference/outpaint.md new file mode 100644 index 0000000000000000000000000000000000000000..f3a7bd99d8fadbe8cd3920e5dd9fab1862a304c9 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/advanced_inference/outpaint.md @@ -0,0 +1,231 @@ + + +# Outpainting + +Outpainting extends an image beyond its original boundaries, allowing you to add, replace, or modify visual elements in an image while preserving the original image. Like [inpainting](../using-diffusers/inpaint), you want to fill the white area (in this case, the area outside of the original image) with new visual elements while keeping the original image (represented by a mask of black pixels). There are a couple of ways to outpaint, such as with a [ControlNet](https://hf.co/blog/OzzyGT/outpainting-controlnet) or with [Differential Diffusion](https://hf.co/blog/OzzyGT/outpainting-differential-diffusion). + +This guide will show you how to outpaint with an inpainting model, ControlNet, and a ZoeDepth estimator. + +Before you begin, make sure you have the [controlnet_aux](https://github.com/huggingface/controlnet_aux) library installed so you can use the ZoeDepth estimator. + +```py +!pip install -q controlnet_aux +``` + +## Image preparation + +Start by picking an image to outpaint with and remove the background with a Space like [BRIA-RMBG-1.4](https://hf.co/spaces/briaai/BRIA-RMBG-1.4). + + + +For example, remove the background from this image of a pair of shoes. + +
+
+ +
original image
+
+
+ +
background removed
+
+
+ +[Stable Diffusion XL (SDXL)](../using-diffusers/sdxl) models work best with 1024x1024 images, but you can resize the image to any size as long as your hardware has enough memory to support it. The transparent background in the image should also be replaced with a white background. Create a function (like the one below) that scales and pastes the image onto a white background. + +```py +import random + +import requests +import torch +from controlnet_aux import ZoeDetector +from PIL import Image, ImageOps + +from diffusers import ( + AutoencoderKL, + ControlNetModel, + StableDiffusionXLControlNetPipeline, + StableDiffusionXLInpaintPipeline, +) + +def scale_and_paste(original_image): + aspect_ratio = original_image.width / original_image.height + + if original_image.width > original_image.height: + new_width = 1024 + new_height = round(new_width / aspect_ratio) + else: + new_height = 1024 + new_width = round(new_height * aspect_ratio) + + resized_original = original_image.resize((new_width, new_height), Image.LANCZOS) + white_background = Image.new("RGBA", (1024, 1024), "white") + x = (1024 - new_width) // 2 + y = (1024 - new_height) // 2 + white_background.paste(resized_original, (x, y), resized_original) + + return resized_original, white_background + +original_image = Image.open( + requests.get( + "https://huggingface.co/datasets/stevhliu/testing-images/resolve/main/no-background-jordan.png", + stream=True, + ).raw +).convert("RGBA") +resized_img, white_bg_image = scale_and_paste(original_image) +``` + +To avoid adding unwanted extra details, use the ZoeDepth estimator to provide additional guidance during generation and to ensure the shoes remain consistent with the original image. + +```py +zoe = ZoeDetector.from_pretrained("lllyasviel/Annotators") +image_zoe = zoe(white_bg_image, detect_resolution=512, image_resolution=1024) +image_zoe +``` + +
+ +
+ +## Outpaint + +Once your image is ready, you can generate content in the white area around the shoes with [controlnet-inpaint-dreamer-sdxl](https://hf.co/destitech/controlnet-inpaint-dreamer-sdxl), a SDXL ControlNet trained for inpainting. + +Load the inpainting ControlNet, ZoeDepth model, VAE and pass them to the [`StableDiffusionXLControlNetPipeline`]. Then you can create an optional `generate_image` function (for convenience) to outpaint an initial image. + +```py +controlnets = [ + ControlNetModel.from_pretrained( + "destitech/controlnet-inpaint-dreamer-sdxl", torch_dtype=torch.float16, variant="fp16" + ), + ControlNetModel.from_pretrained( + "diffusers/controlnet-zoe-depth-sdxl-1.0", torch_dtype=torch.float16 + ), +] +vae = AutoencoderKL.from_pretrained("madebyollin/sdxl-vae-fp16-fix", torch_dtype=torch.float16).to("cuda") +pipeline = StableDiffusionXLControlNetPipeline.from_pretrained( + "SG161222/RealVisXL_V4.0", torch_dtype=torch.float16, variant="fp16", controlnet=controlnets, vae=vae +).to("cuda") + +def generate_image(prompt, negative_prompt, inpaint_image, zoe_image, seed: int = None): + if seed is None: + seed = random.randint(0, 2**32 - 1) + + generator = torch.Generator(device="cpu").manual_seed(seed) + + image = pipeline( + prompt, + negative_prompt=negative_prompt, + image=[inpaint_image, zoe_image], + guidance_scale=6.5, + num_inference_steps=25, + generator=generator, + controlnet_conditioning_scale=[0.5, 0.8], + control_guidance_end=[0.9, 0.6], + ).images[0] + + return image + +prompt = "nike air jordans on a basketball court" +negative_prompt = "" + +temp_image = generate_image(prompt, negative_prompt, white_bg_image, image_zoe, 908097) +``` + +Paste the original image over the initial outpainted image. You'll improve the outpainted background in a later step. + +```py +x = (1024 - resized_img.width) // 2 +y = (1024 - resized_img.height) // 2 +temp_image.paste(resized_img, (x, y), resized_img) +temp_image +``` + +
+ +
+ +> [!TIP] +> Now is a good time to free up some memory if you're running low! +> +> ```py +> pipeline=None +> torch.cuda.empty_cache() +> ``` + +Now that you have an initial outpainted image, load the [`StableDiffusionXLInpaintPipeline`] with the [RealVisXL](https://hf.co/SG161222/RealVisXL_V4.0) model to generate the final outpainted image with better quality. + +```py +pipeline = StableDiffusionXLInpaintPipeline.from_pretrained( + "OzzyGT/RealVisXL_V4.0_inpainting", + torch_dtype=torch.float16, + variant="fp16", + vae=vae, +).to("cuda") +``` + +Prepare a mask for the final outpainted image. To create a more natural transition between the original image and the outpainted background, blur the mask to help it blend better. + +```py +mask = Image.new("L", temp_image.size) +mask.paste(resized_img.split()[3], (x, y)) +mask = ImageOps.invert(mask) +final_mask = mask.point(lambda p: p > 128 and 255) +mask_blurred = pipeline.mask_processor.blur(final_mask, blur_factor=20) +mask_blurred +``` + +
+ +
+ +Create a better prompt and pass it to the `generate_outpaint` function to generate the final outpainted image. Again, paste the original image over the final outpainted background. + +```py +def generate_outpaint(prompt, negative_prompt, image, mask, seed: int = None): + if seed is None: + seed = random.randint(0, 2**32 - 1) + + generator = torch.Generator(device="cpu").manual_seed(seed) + + image = pipeline( + prompt, + negative_prompt=negative_prompt, + image=image, + mask_image=mask, + guidance_scale=10.0, + strength=0.8, + num_inference_steps=30, + generator=generator, + ).images[0] + + return image + +prompt = "high quality photo of nike air jordans on a basketball court, highly detailed" +negative_prompt = "" + +final_image = generate_outpaint(prompt, negative_prompt, temp_image, mask_blurred, 7688778) +x = (1024 - resized_img.width) // 2 +y = (1024 - resized_img.height) // 2 +final_image.paste(resized_img, (x, y), resized_img) +final_image +``` + +
+ +
diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/activations.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/activations.md new file mode 100644 index 0000000000000000000000000000000000000000..140a2ae1a1b27f05df35f09af34b62d33e01fed5 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/activations.md @@ -0,0 +1,40 @@ + + +# Activation functions + +Customized activation functions for supporting various models in 🤗 Diffusers. + +## GELU + +[[autodoc]] models.activations.GELU + +## GEGLU + +[[autodoc]] models.activations.GEGLU + +## ApproximateGELU + +[[autodoc]] models.activations.ApproximateGELU + + +## SwiGLU + +[[autodoc]] models.activations.SwiGLU + +## FP32SiLU + +[[autodoc]] models.activations.FP32SiLU + +## LinearActivation + +[[autodoc]] models.activations.LinearActivation diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/attnprocessor.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/attnprocessor.md new file mode 100644 index 0000000000000000000000000000000000000000..638ecb973e5d5bb4176ae4dd4e0bd3289b1eaab9 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/attnprocessor.md @@ -0,0 +1,166 @@ + + +# Attention Processor + +An attention processor is a class for applying different types of attention mechanisms. + +## AttnProcessor + +[[autodoc]] models.attention_processor.AttnProcessor + +[[autodoc]] models.attention_processor.AttnProcessor2_0 + +[[autodoc]] models.attention_processor.AttnAddedKVProcessor + +[[autodoc]] models.attention_processor.AttnAddedKVProcessor2_0 + +[[autodoc]] models.attention_processor.AttnProcessorNPU + +[[autodoc]] models.attention_processor.FusedAttnProcessor2_0 + +## Allegro + +[[autodoc]] models.attention_processor.AllegroAttnProcessor2_0 + +## AuraFlow + +[[autodoc]] models.attention_processor.AuraFlowAttnProcessor2_0 + +[[autodoc]] models.attention_processor.FusedAuraFlowAttnProcessor2_0 + +## CogVideoX + +[[autodoc]] models.attention_processor.CogVideoXAttnProcessor2_0 + +[[autodoc]] models.attention_processor.FusedCogVideoXAttnProcessor2_0 + +## CrossFrameAttnProcessor + +[[autodoc]] pipelines.text_to_video_synthesis.pipeline_text_to_video_zero.CrossFrameAttnProcessor + +## Custom Diffusion + +[[autodoc]] models.attention_processor.CustomDiffusionAttnProcessor + +[[autodoc]] models.attention_processor.CustomDiffusionAttnProcessor2_0 + +[[autodoc]] models.attention_processor.CustomDiffusionXFormersAttnProcessor + +## Flux + +[[autodoc]] models.attention_processor.FluxAttnProcessor2_0 + +[[autodoc]] models.attention_processor.FusedFluxAttnProcessor2_0 + +[[autodoc]] models.attention_processor.FluxSingleAttnProcessor2_0 + +## Hunyuan + +[[autodoc]] models.attention_processor.HunyuanAttnProcessor2_0 + +[[autodoc]] models.attention_processor.FusedHunyuanAttnProcessor2_0 + +[[autodoc]] models.attention_processor.PAGHunyuanAttnProcessor2_0 + +[[autodoc]] models.attention_processor.PAGCFGHunyuanAttnProcessor2_0 + +## IdentitySelfAttnProcessor2_0 + +[[autodoc]] models.attention_processor.PAGIdentitySelfAttnProcessor2_0 + +[[autodoc]] models.attention_processor.PAGCFGIdentitySelfAttnProcessor2_0 + +## IP-Adapter + +[[autodoc]] models.attention_processor.IPAdapterAttnProcessor + +[[autodoc]] models.attention_processor.IPAdapterAttnProcessor2_0 + +[[autodoc]] models.attention_processor.SD3IPAdapterJointAttnProcessor2_0 + +## JointAttnProcessor2_0 + +[[autodoc]] models.attention_processor.JointAttnProcessor2_0 + +[[autodoc]] models.attention_processor.PAGJointAttnProcessor2_0 + +[[autodoc]] models.attention_processor.PAGCFGJointAttnProcessor2_0 + +[[autodoc]] models.attention_processor.FusedJointAttnProcessor2_0 + +## LoRA + +[[autodoc]] models.attention_processor.LoRAAttnProcessor + +[[autodoc]] models.attention_processor.LoRAAttnProcessor2_0 + +[[autodoc]] models.attention_processor.LoRAAttnAddedKVProcessor + +[[autodoc]] models.attention_processor.LoRAXFormersAttnProcessor + +## Lumina-T2X + +[[autodoc]] models.attention_processor.LuminaAttnProcessor2_0 + +## Mochi + +[[autodoc]] models.attention_processor.MochiAttnProcessor2_0 + +[[autodoc]] models.attention_processor.MochiVaeAttnProcessor2_0 + +## Sana + +[[autodoc]] models.attention_processor.SanaLinearAttnProcessor2_0 + +[[autodoc]] models.attention_processor.SanaMultiscaleAttnProcessor2_0 + +[[autodoc]] models.attention_processor.PAGCFGSanaLinearAttnProcessor2_0 + +[[autodoc]] models.attention_processor.PAGIdentitySanaLinearAttnProcessor2_0 + +## Stable Audio + +[[autodoc]] models.attention_processor.StableAudioAttnProcessor2_0 + +## SlicedAttnProcessor + +[[autodoc]] models.attention_processor.SlicedAttnProcessor + +[[autodoc]] models.attention_processor.SlicedAttnAddedKVProcessor + +## XFormersAttnProcessor + +[[autodoc]] models.attention_processor.XFormersAttnProcessor + +[[autodoc]] models.attention_processor.XFormersAttnAddedKVProcessor + +## XLAFlashAttnProcessor2_0 + +[[autodoc]] models.attention_processor.XLAFlashAttnProcessor2_0 + +## XFormersJointAttnProcessor + +[[autodoc]] models.attention_processor.XFormersJointAttnProcessor + +## IPAdapterXFormersAttnProcessor + +[[autodoc]] models.attention_processor.IPAdapterXFormersAttnProcessor + +## FluxIPAdapterJointAttnProcessor2_0 + +[[autodoc]] models.attention_processor.FluxIPAdapterJointAttnProcessor2_0 + + +## XLAFluxFlashAttnProcessor2_0 + +[[autodoc]] models.attention_processor.XLAFluxFlashAttnProcessor2_0 \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/cache.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/cache.md new file mode 100644 index 0000000000000000000000000000000000000000..a6aa5445a845b25a640c764e0e6bfc0127389ee5 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/cache.md @@ -0,0 +1,82 @@ + + +# Caching methods + +## Pyramid Attention Broadcast + +[Pyramid Attention Broadcast](https://huggingface.co/papers/2408.12588) from Xuanlei Zhao, Xiaolong Jin, Kai Wang, Yang You. + +Pyramid Attention Broadcast (PAB) is a method that speeds up inference in diffusion models by systematically skipping attention computations between successive inference steps and reusing cached attention states. The attention states are not very different between successive inference steps. The most prominent difference is in the spatial attention blocks, not as much in the temporal attention blocks, and finally the least in the cross attention blocks. Therefore, many cross attention computation blocks can be skipped, followed by the temporal and spatial attention blocks. By combining other techniques like sequence parallelism and classifier-free guidance parallelism, PAB achieves near real-time video generation. + +Enable PAB with [`~PyramidAttentionBroadcastConfig`] on any pipeline. For some benchmarks, refer to [this](https://github.com/huggingface/diffusers/pull/9562) pull request. + +```python +import torch +from diffusers import CogVideoXPipeline, PyramidAttentionBroadcastConfig + +pipe = CogVideoXPipeline.from_pretrained("THUDM/CogVideoX-5b", torch_dtype=torch.bfloat16) +pipe.to("cuda") + +# Increasing the value of `spatial_attention_timestep_skip_range[0]` or decreasing the value of +# `spatial_attention_timestep_skip_range[1]` will decrease the interval in which pyramid attention +# broadcast is active, leader to slower inference speeds. However, large intervals can lead to +# poorer quality of generated videos. +config = PyramidAttentionBroadcastConfig( + spatial_attention_block_skip_range=2, + spatial_attention_timestep_skip_range=(100, 800), + current_timestep_callback=lambda: pipe.current_timestep, +) +pipe.transformer.enable_cache(config) +``` + +## Faster Cache + +[FasterCache](https://huggingface.co/papers/2410.19355) from Zhengyao Lv, Chenyang Si, Junhao Song, Zhenyu Yang, Yu Qiao, Ziwei Liu, Kwan-Yee K. Wong. + +FasterCache is a method that speeds up inference in diffusion transformers by: +- Reusing attention states between successive inference steps, due to high similarity between them +- Skipping unconditional branch prediction used in classifier-free guidance by revealing redundancies between unconditional and conditional branch outputs for the same timestep, and therefore approximating the unconditional branch output using the conditional branch output + +```python +import torch +from diffusers import CogVideoXPipeline, FasterCacheConfig + +pipe = CogVideoXPipeline.from_pretrained("THUDM/CogVideoX-5b", torch_dtype=torch.bfloat16) +pipe.to("cuda") + +config = FasterCacheConfig( + spatial_attention_block_skip_range=2, + spatial_attention_timestep_skip_range=(-1, 681), + current_timestep_callback=lambda: pipe.current_timestep, + attention_weight_callback=lambda _: 0.3, + unconditional_batch_skip_range=5, + unconditional_batch_timestep_skip_range=(-1, 781), + tensor_format="BFCHW", +) +pipe.transformer.enable_cache(config) +``` + +### CacheMixin + +[[autodoc]] CacheMixin + +### PyramidAttentionBroadcastConfig + +[[autodoc]] PyramidAttentionBroadcastConfig + +[[autodoc]] apply_pyramid_attention_broadcast + +### FasterCacheConfig + +[[autodoc]] FasterCacheConfig + +[[autodoc]] apply_faster_cache diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/configuration.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/configuration.md new file mode 100644 index 0000000000000000000000000000000000000000..31d70232a95c1b610030c983e75045e286280327 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/configuration.md @@ -0,0 +1,30 @@ + + +# Configuration + +Schedulers from [`~schedulers.scheduling_utils.SchedulerMixin`] and models from [`ModelMixin`] inherit from [`ConfigMixin`] which stores all the parameters that are passed to their respective `__init__` methods in a JSON-configuration file. + + + +To use private or [gated](https://huggingface.co/docs/hub/models-gated#gated-models) models, log-in with `huggingface-cli login`. + + + +## ConfigMixin + +[[autodoc]] ConfigMixin + - load_config + - from_config + - save_config + - to_json_file + - to_json_string diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/image_processor.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/image_processor.md new file mode 100644 index 0000000000000000000000000000000000000000..e633a936103da470b8c5767d14da6926af5fb88d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/image_processor.md @@ -0,0 +1,35 @@ + + +# VAE Image Processor + +The [`VaeImageProcessor`] provides a unified API for [`StableDiffusionPipeline`]s to prepare image inputs for VAE encoding and post-processing outputs once they're decoded. This includes transformations such as resizing, normalization, and conversion between PIL Image, PyTorch, and NumPy arrays. + +All pipelines with [`VaeImageProcessor`] accept PIL Image, PyTorch tensor, or NumPy arrays as image inputs and return outputs based on the `output_type` argument by the user. You can pass encoded image latents directly to the pipeline and return latents from the pipeline as a specific output with the `output_type` argument (for example `output_type="latent"`). This allows you to take the generated latents from one pipeline and pass it to another pipeline as input without leaving the latent space. It also makes it much easier to use multiple pipelines together by passing PyTorch tensors directly between different pipelines. + +## VaeImageProcessor + +[[autodoc]] image_processor.VaeImageProcessor + +## VaeImageProcessorLDM3D + +The [`VaeImageProcessorLDM3D`] accepts RGB and depth inputs and returns RGB and depth outputs. + +[[autodoc]] image_processor.VaeImageProcessorLDM3D + +## PixArtImageProcessor + +[[autodoc]] image_processor.PixArtImageProcessor + +## IPAdapterMaskProcessor + +[[autodoc]] image_processor.IPAdapterMaskProcessor diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/internal_classes_overview.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/internal_classes_overview.md new file mode 100644 index 0000000000000000000000000000000000000000..38e8124cd4a00609b29470b705e30b3ca4791bc2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/internal_classes_overview.md @@ -0,0 +1,15 @@ + + +# Overview + +The APIs in this section are more experimental and prone to breaking changes. Most of them are used internally for development, but they may also be useful to you if you're interested in building a diffusion model with some custom parts or if you're interested in some of our helper utilities for working with 🤗 Diffusers. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/ip_adapter.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/ip_adapter.md new file mode 100644 index 0000000000000000000000000000000000000000..946a8b1af8759c98c7fba41631eb156c162d6855 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/ip_adapter.md @@ -0,0 +1,35 @@ + + +# IP-Adapter + +[IP-Adapter](https://hf.co/papers/2308.06721) is a lightweight adapter that enables prompting a diffusion model with an image. This method decouples the cross-attention layers of the image and text features. The image features are generated from an image encoder. + + + +Learn how to load an IP-Adapter checkpoint and image in the IP-Adapter [loading](../../using-diffusers/loading_adapters#ip-adapter) guide, and you can see how to use it in the [usage](../../using-diffusers/ip_adapter) guide. + + + +## IPAdapterMixin + +[[autodoc]] loaders.ip_adapter.IPAdapterMixin + +## SD3IPAdapterMixin + +[[autodoc]] loaders.ip_adapter.SD3IPAdapterMixin + - all + - is_ip_adapter_active + +## IPAdapterMaskProcessor + +[[autodoc]] image_processor.IPAdapterMaskProcessor \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/lora.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/lora.md new file mode 100644 index 0000000000000000000000000000000000000000..1c716f6d5e85c62d8ccc0e873ba3f42b2c99ee5c --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/lora.md @@ -0,0 +1,101 @@ + + +# LoRA + +LoRA is a fast and lightweight training method that inserts and trains a significantly smaller number of parameters instead of all the model parameters. This produces a smaller file (~100 MBs) and makes it easier to quickly train a model to learn a new concept. LoRA weights are typically loaded into the denoiser, text encoder or both. The denoiser usually corresponds to a UNet ([`UNet2DConditionModel`], for example) or a Transformer ([`SD3Transformer2DModel`], for example). There are several classes for loading LoRA weights: + +- [`StableDiffusionLoraLoaderMixin`] provides functions for loading and unloading, fusing and unfusing, enabling and disabling, and more functions for managing LoRA weights. This class can be used with any model. +- [`StableDiffusionXLLoraLoaderMixin`] is a [Stable Diffusion (SDXL)](../../api/pipelines/stable_diffusion/stable_diffusion_xl) version of the [`StableDiffusionLoraLoaderMixin`] class for loading and saving LoRA weights. It can only be used with the SDXL model. +- [`SD3LoraLoaderMixin`] provides similar functions for [Stable Diffusion 3](https://huggingface.co/blog/sd3). +- [`FluxLoraLoaderMixin`] provides similar functions for [Flux](https://huggingface.co/docs/diffusers/main/en/api/pipelines/flux). +- [`CogVideoXLoraLoaderMixin`] provides similar functions for [CogVideoX](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogvideox). +- [`Mochi1LoraLoaderMixin`] provides similar functions for [Mochi](https://huggingface.co/docs/diffusers/main/en/api/pipelines/mochi). +- [`AuraFlowLoraLoaderMixin`] provides similar functions for [AuraFlow](https://huggingface.co/fal/AuraFlow). +- [`LTXVideoLoraLoaderMixin`] provides similar functions for [LTX-Video](https://huggingface.co/docs/diffusers/main/en/api/pipelines/ltx_video). +- [`SanaLoraLoaderMixin`] provides similar functions for [Sana](https://huggingface.co/docs/diffusers/main/en/api/pipelines/sana). +- [`HunyuanVideoLoraLoaderMixin`] provides similar functions for [HunyuanVideo](https://huggingface.co/docs/diffusers/main/en/api/pipelines/hunyuan_video). +- [`Lumina2LoraLoaderMixin`] provides similar functions for [Lumina2](https://huggingface.co/docs/diffusers/main/en/api/pipelines/lumina2). +- [`WanLoraLoaderMixin`] provides similar functions for [Wan](https://huggingface.co/docs/diffusers/main/en/api/pipelines/wan). +- [`CogView4LoraLoaderMixin`] provides similar functions for [CogView4](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogview4). +- [`AmusedLoraLoaderMixin`] is for the [`AmusedPipeline`]. +- [`HiDreamImageLoraLoaderMixin`] provides similar functions for [HiDream Image](https://huggingface.co/docs/diffusers/main/en/api/pipelines/hidream) +- [`LoraBaseMixin`] provides a base class with several utility methods to fuse, unfuse, unload, LoRAs and more. + + + +To learn more about how to load LoRA weights, see the [LoRA](../../using-diffusers/loading_adapters#lora) loading guide. + + + +## StableDiffusionLoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.StableDiffusionLoraLoaderMixin + +## StableDiffusionXLLoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.StableDiffusionXLLoraLoaderMixin + +## SD3LoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.SD3LoraLoaderMixin + +## FluxLoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.FluxLoraLoaderMixin + +## CogVideoXLoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.CogVideoXLoraLoaderMixin + +## Mochi1LoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.Mochi1LoraLoaderMixin +## AuraFlowLoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.AuraFlowLoraLoaderMixin + +## LTXVideoLoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.LTXVideoLoraLoaderMixin + +## SanaLoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.SanaLoraLoaderMixin + +## HunyuanVideoLoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.HunyuanVideoLoraLoaderMixin + +## Lumina2LoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.Lumina2LoraLoaderMixin + +## CogView4LoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.CogView4LoraLoaderMixin + +## WanLoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.WanLoraLoaderMixin + +## AmusedLoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.AmusedLoraLoaderMixin + +## HiDreamImageLoraLoaderMixin + +[[autodoc]] loaders.lora_pipeline.HiDreamImageLoraLoaderMixin + +## LoraBaseMixin + +[[autodoc]] loaders.lora_base.LoraBaseMixin \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/peft.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/peft.md new file mode 100644 index 0000000000000000000000000000000000000000..67a4a7f2a490b17cd8a8eeea74a50cb45958e4c3 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/peft.md @@ -0,0 +1,25 @@ + + +# PEFT + +Diffusers supports loading adapters such as [LoRA](../../using-diffusers/loading_adapters) with the [PEFT](https://huggingface.co/docs/peft/index) library with the [`~loaders.peft.PeftAdapterMixin`] class. This allows modeling classes in Diffusers like [`UNet2DConditionModel`], [`SD3Transformer2DModel`] to operate with an adapter. + + + +Refer to the [Inference with PEFT](../../tutorials/using_peft_for_inference.md) tutorial for an overview of how to use PEFT in Diffusers for inference. + + + +## PeftAdapterMixin + +[[autodoc]] loaders.peft.PeftAdapterMixin diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/single_file.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/single_file.md new file mode 100644 index 0000000000000000000000000000000000000000..64ca02fd83870f41d12a2c5adbd79648c80dd46a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/single_file.md @@ -0,0 +1,62 @@ + + +# Single files + +The [`~loaders.FromSingleFileMixin.from_single_file`] method allows you to load: + +* a model stored in a single file, which is useful if you're working with models from the diffusion ecosystem, like Automatic1111, and commonly rely on a single-file layout to store and share models +* a model stored in their originally distributed layout, which is useful if you're working with models finetuned with other services, and want to load it directly into Diffusers model objects and pipelines + +> [!TIP] +> Read the [Model files and layouts](../../using-diffusers/other-formats) guide to learn more about the Diffusers-multifolder layout versus the single-file layout, and how to load models stored in these different layouts. + +## Supported pipelines + +- [`StableDiffusionPipeline`] +- [`StableDiffusionImg2ImgPipeline`] +- [`StableDiffusionInpaintPipeline`] +- [`StableDiffusionControlNetPipeline`] +- [`StableDiffusionControlNetImg2ImgPipeline`] +- [`StableDiffusionControlNetInpaintPipeline`] +- [`StableDiffusionUpscalePipeline`] +- [`StableDiffusionXLPipeline`] +- [`StableDiffusionXLImg2ImgPipeline`] +- [`StableDiffusionXLInpaintPipeline`] +- [`StableDiffusionXLInstructPix2PixPipeline`] +- [`StableDiffusionXLControlNetPipeline`] +- [`StableDiffusionXLKDiffusionPipeline`] +- [`StableDiffusion3Pipeline`] +- [`LatentConsistencyModelPipeline`] +- [`LatentConsistencyModelImg2ImgPipeline`] +- [`StableDiffusionControlNetXSPipeline`] +- [`StableDiffusionXLControlNetXSPipeline`] +- [`LEditsPPPipelineStableDiffusion`] +- [`LEditsPPPipelineStableDiffusionXL`] +- [`PIAPipeline`] + +## Supported models + +- [`UNet2DConditionModel`] +- [`StableCascadeUNet`] +- [`AutoencoderKL`] +- [`ControlNetModel`] +- [`SD3Transformer2DModel`] +- [`FluxTransformer2DModel`] + +## FromSingleFileMixin + +[[autodoc]] loaders.single_file.FromSingleFileMixin + +## FromOriginalModelMixin + +[[autodoc]] loaders.single_file_model.FromOriginalModelMixin diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/textual_inversion.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/textual_inversion.md new file mode 100644 index 0000000000000000000000000000000000000000..c900e22af847167a3738eb0ba9aec766919c630e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/textual_inversion.md @@ -0,0 +1,27 @@ + + +# Textual Inversion + +Textual Inversion is a training method for personalizing models by learning new text embeddings from a few example images. The file produced from training is extremely small (a few KBs) and the new embeddings can be loaded into the text encoder. + +[`TextualInversionLoaderMixin`] provides a function for loading Textual Inversion embeddings from Diffusers and Automatic1111 into the text encoder and loading a special token to activate the embeddings. + + + +To learn more about how to load Textual Inversion embeddings, see the [Textual Inversion](../../using-diffusers/loading_adapters#textual-inversion) loading guide. + + + +## TextualInversionLoaderMixin + +[[autodoc]] loaders.textual_inversion.TextualInversionLoaderMixin \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/transformer_sd3.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/transformer_sd3.md new file mode 100644 index 0000000000000000000000000000000000000000..4fc9603054b479f18c47cb0251acbaafb1113805 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/transformer_sd3.md @@ -0,0 +1,29 @@ + + +# SD3Transformer2D + +This class is useful when *only* loading weights into a [`SD3Transformer2DModel`]. If you need to load weights into the text encoder or a text encoder and SD3Transformer2DModel, check [`SD3LoraLoaderMixin`](lora#diffusers.loaders.SD3LoraLoaderMixin) class instead. + +The [`SD3Transformer2DLoadersMixin`] class currently only loads IP-Adapter weights, but will be used in the future to save weights and load LoRAs. + + + +To learn more about how to load LoRA weights, see the [LoRA](../../using-diffusers/loading_adapters#lora) loading guide. + + + +## SD3Transformer2DLoadersMixin + +[[autodoc]] loaders.transformer_sd3.SD3Transformer2DLoadersMixin + - all + - _load_ip_adapter_weights \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/unet.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/unet.md new file mode 100644 index 0000000000000000000000000000000000000000..16cc319b4ed02a46e287fac88d81e1e21799938a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/loaders/unet.md @@ -0,0 +1,27 @@ + + +# UNet + +Some training methods - like LoRA and Custom Diffusion - typically target the UNet's attention layers, but these training methods can also target other non-attention layers. Instead of training all of a model's parameters, only a subset of the parameters are trained, which is faster and more efficient. This class is useful if you're *only* loading weights into a UNet. If you need to load weights into the text encoder or a text encoder and UNet, try using the [`~loaders.StableDiffusionLoraLoaderMixin.load_lora_weights`] function instead. + +The [`UNet2DConditionLoadersMixin`] class provides functions for loading and saving weights, fusing and unfusing LoRAs, disabling and enabling LoRAs, and setting and deleting adapters. + + + +To learn more about how to load LoRA weights, see the [LoRA](../../using-diffusers/loading_adapters#lora) loading guide. + + + +## UNet2DConditionLoadersMixin + +[[autodoc]] loaders.unet.UNet2DConditionLoadersMixin \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/logging.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/logging.md new file mode 100644 index 0000000000000000000000000000000000000000..1b219645da6b904d1bbb4c18d35f5f3796ed326e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/logging.md @@ -0,0 +1,96 @@ + + +# Logging + +🤗 Diffusers has a centralized logging system to easily manage the verbosity of the library. The default verbosity is set to `WARNING`. + +To change the verbosity level, use one of the direct setters. For instance, to change the verbosity to the `INFO` level. + +```python +import diffusers + +diffusers.logging.set_verbosity_info() +``` + +You can also use the environment variable `DIFFUSERS_VERBOSITY` to override the default verbosity. You can set it +to one of the following: `debug`, `info`, `warning`, `error`, `critical`. For example: + +```bash +DIFFUSERS_VERBOSITY=error ./myprogram.py +``` + +Additionally, some `warnings` can be disabled by setting the environment variable +`DIFFUSERS_NO_ADVISORY_WARNINGS` to a true value, like `1`. This disables any warning logged by +[`logger.warning_advice`]. For example: + +```bash +DIFFUSERS_NO_ADVISORY_WARNINGS=1 ./myprogram.py +``` + +Here is an example of how to use the same logger as the library in your own module or script: + +```python +from diffusers.utils import logging + +logging.set_verbosity_info() +logger = logging.get_logger("diffusers") +logger.info("INFO") +logger.warning("WARN") +``` + + +All methods of the logging module are documented below. The main methods are +[`logging.get_verbosity`] to get the current level of verbosity in the logger and +[`logging.set_verbosity`] to set the verbosity to the level of your choice. + +In order from the least verbose to the most verbose: + +| Method | Integer value | Description | +|----------------------------------------------------------:|--------------:|----------------------------------------------------:| +| `diffusers.logging.CRITICAL` or `diffusers.logging.FATAL` | 50 | only report the most critical errors | +| `diffusers.logging.ERROR` | 40 | only report errors | +| `diffusers.logging.WARNING` or `diffusers.logging.WARN` | 30 | only report errors and warnings (default) | +| `diffusers.logging.INFO` | 20 | only report errors, warnings, and basic information | +| `diffusers.logging.DEBUG` | 10 | report all information | + +By default, `tqdm` progress bars are displayed during model download. [`logging.disable_progress_bar`] and [`logging.enable_progress_bar`] are used to enable or disable this behavior. + +## Base setters + +[[autodoc]] utils.logging.set_verbosity_error + +[[autodoc]] utils.logging.set_verbosity_warning + +[[autodoc]] utils.logging.set_verbosity_info + +[[autodoc]] utils.logging.set_verbosity_debug + +## Other functions + +[[autodoc]] utils.logging.get_verbosity + +[[autodoc]] utils.logging.set_verbosity + +[[autodoc]] utils.logging.get_logger + +[[autodoc]] utils.logging.enable_default_handler + +[[autodoc]] utils.logging.disable_default_handler + +[[autodoc]] utils.logging.enable_explicit_format + +[[autodoc]] utils.logging.reset_format + +[[autodoc]] utils.logging.enable_progress_bar + +[[autodoc]] utils.logging.disable_progress_bar diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/allegro_transformer3d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/allegro_transformer3d.md new file mode 100644 index 0000000000000000000000000000000000000000..7b035cd05535063f6531ce8fe09de94e7b76a7f2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/allegro_transformer3d.md @@ -0,0 +1,30 @@ + + +# AllegroTransformer3DModel + +A Diffusion Transformer model for 3D data from [Allegro](https://github.com/rhymes-ai/Allegro) was introduced in [Allegro: Open the Black Box of Commercial-Level Video Generation Model](https://huggingface.co/papers/2410.15458) by RhymesAI. + +The model can be loaded with the following code snippet. + +```python +from diffusers import AllegroTransformer3DModel + +transformer = AllegroTransformer3DModel.from_pretrained("rhymes-ai/Allegro", subfolder="transformer", torch_dtype=torch.bfloat16).to("cuda") +``` + +## AllegroTransformer3DModel + +[[autodoc]] AllegroTransformer3DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/asymmetricautoencoderkl.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/asymmetricautoencoderkl.md new file mode 100644 index 0000000000000000000000000000000000000000..d29be2ccb22a52de6f83c907f2c684019b5d0fb7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/asymmetricautoencoderkl.md @@ -0,0 +1,60 @@ + + +# AsymmetricAutoencoderKL + +Improved larger variational autoencoder (VAE) model with KL loss for inpainting task: [Designing a Better Asymmetric VQGAN for StableDiffusion](https://huggingface.co/papers/2306.04632) by Zixin Zhu, Xuelu Feng, Dongdong Chen, Jianmin Bao, Le Wang, Yinpeng Chen, Lu Yuan, Gang Hua. + +The abstract from the paper is: + +*StableDiffusion is a revolutionary text-to-image generator that is causing a stir in the world of image generation and editing. Unlike traditional methods that learn a diffusion model in pixel space, StableDiffusion learns a diffusion model in the latent space via a VQGAN, ensuring both efficiency and quality. It not only supports image generation tasks, but also enables image editing for real images, such as image inpainting and local editing. However, we have observed that the vanilla VQGAN used in StableDiffusion leads to significant information loss, causing distortion artifacts even in non-edited image regions. To this end, we propose a new asymmetric VQGAN with two simple designs. Firstly, in addition to the input from the encoder, the decoder contains a conditional branch that incorporates information from task-specific priors, such as the unmasked image region in inpainting. Secondly, the decoder is much heavier than the encoder, allowing for more detailed recovery while only slightly increasing the total inference cost. The training cost of our asymmetric VQGAN is cheap, and we only need to retrain a new asymmetric decoder while keeping the vanilla VQGAN encoder and StableDiffusion unchanged. Our asymmetric VQGAN can be widely used in StableDiffusion-based inpainting and local editing methods. Extensive experiments demonstrate that it can significantly improve the inpainting and editing performance, while maintaining the original text-to-image capability. The code is available at https://github.com/buxiangzhiren/Asymmetric_VQGAN* + +Evaluation results can be found in section 4.1 of the original paper. + +## Available checkpoints + +* [https://huggingface.co/cross-attention/asymmetric-autoencoder-kl-x-1-5](https://huggingface.co/cross-attention/asymmetric-autoencoder-kl-x-1-5) +* [https://huggingface.co/cross-attention/asymmetric-autoencoder-kl-x-2](https://huggingface.co/cross-attention/asymmetric-autoencoder-kl-x-2) + +## Example Usage + +```python +from diffusers import AsymmetricAutoencoderKL, StableDiffusionInpaintPipeline +from diffusers.utils import load_image, make_image_grid + + +prompt = "a photo of a person with beard" +img_url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/repaint/celeba_hq_256.png" +mask_url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/repaint/mask_256.png" + +original_image = load_image(img_url).resize((512, 512)) +mask_image = load_image(mask_url).resize((512, 512)) + +pipe = StableDiffusionInpaintPipeline.from_pretrained("runwayml/stable-diffusion-inpainting") +pipe.vae = AsymmetricAutoencoderKL.from_pretrained("cross-attention/asymmetric-autoencoder-kl-x-1-5") +pipe.to("cuda") + +image = pipe(prompt=prompt, image=original_image, mask_image=mask_image).images[0] +make_image_grid([original_image, mask_image, image], rows=1, cols=3) +``` + +## AsymmetricAutoencoderKL + +[[autodoc]] models.autoencoders.autoencoder_asym_kl.AsymmetricAutoencoderKL + +## AutoencoderKLOutput + +[[autodoc]] models.autoencoders.autoencoder_kl.AutoencoderKLOutput + +## DecoderOutput + +[[autodoc]] models.autoencoders.vae.DecoderOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/aura_flow_transformer2d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/aura_flow_transformer2d.md new file mode 100644 index 0000000000000000000000000000000000000000..d07806bcc2155362dfa9e09a164e021969b488e0 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/aura_flow_transformer2d.md @@ -0,0 +1,19 @@ + + +# AuraFlowTransformer2DModel + +A Transformer model for image-like data from [AuraFlow](https://blog.fal.ai/auraflow/). + +## AuraFlowTransformer2DModel + +[[autodoc]] AuraFlowTransformer2DModel diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/auto_model.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/auto_model.md new file mode 100644 index 0000000000000000000000000000000000000000..ebec36c03c1db908fae667e2b52a1be45a7618f6 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/auto_model.md @@ -0,0 +1,29 @@ + + +# AutoModel + +The `AutoModel` is designed to make it easy to load a checkpoint without needing to know the specific model class. `AutoModel` automatically retrieves the correct model class from the checkpoint `config.json` file. + +```python +from diffusers import AutoModel, AutoPipelineForText2Image + +unet = AutoModel.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", subfolder="unet") +pipe = AutoPipelineForText2Image.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", unet=unet) +``` + + +## AutoModel + +[[autodoc]] AutoModel + - all + - from_pretrained diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_dc.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_dc.md new file mode 100644 index 0000000000000000000000000000000000000000..6f86150eb744da17cc40e66b4a2c88f913c238da --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_dc.md @@ -0,0 +1,72 @@ + + +# AutoencoderDC + +The 2D Autoencoder model used in [SANA](https://huggingface.co/papers/2410.10629) and introduced in [DCAE](https://huggingface.co/papers/2410.10733) by authors Junyu Chen\*, Han Cai\*, Junsong Chen, Enze Xie, Shang Yang, Haotian Tang, Muyang Li, Yao Lu, Song Han from MIT HAN Lab. + +The abstract from the paper is: + +*We present Deep Compression Autoencoder (DC-AE), a new family of autoencoder models for accelerating high-resolution diffusion models. Existing autoencoder models have demonstrated impressive results at a moderate spatial compression ratio (e.g., 8x), but fail to maintain satisfactory reconstruction accuracy for high spatial compression ratios (e.g., 64x). We address this challenge by introducing two key techniques: (1) Residual Autoencoding, where we design our models to learn residuals based on the space-to-channel transformed features to alleviate the optimization difficulty of high spatial-compression autoencoders; (2) Decoupled High-Resolution Adaptation, an efficient decoupled three-phases training strategy for mitigating the generalization penalty of high spatial-compression autoencoders. With these designs, we improve the autoencoder's spatial compression ratio up to 128 while maintaining the reconstruction quality. Applying our DC-AE to latent diffusion models, we achieve significant speedup without accuracy drop. For example, on ImageNet 512x512, our DC-AE provides 19.1x inference speedup and 17.9x training speedup on H100 GPU for UViT-H while achieving a better FID, compared with the widely used SD-VAE-f8 autoencoder. Our code is available at [this https URL](https://github.com/mit-han-lab/efficientvit).* + +The following DCAE models are released and supported in Diffusers. + +| Diffusers format | Original format | +|:----------------:|:---------------:| +| [`mit-han-lab/dc-ae-f32c32-sana-1.0-diffusers`](https://huggingface.co/mit-han-lab/dc-ae-f32c32-sana-1.0-diffusers) | [`mit-han-lab/dc-ae-f32c32-sana-1.0`](https://huggingface.co/mit-han-lab/dc-ae-f32c32-sana-1.0) +| [`mit-han-lab/dc-ae-f32c32-in-1.0-diffusers`](https://huggingface.co/mit-han-lab/dc-ae-f32c32-in-1.0-diffusers) | [`mit-han-lab/dc-ae-f32c32-in-1.0`](https://huggingface.co/mit-han-lab/dc-ae-f32c32-in-1.0) +| [`mit-han-lab/dc-ae-f32c32-mix-1.0-diffusers`](https://huggingface.co/mit-han-lab/dc-ae-f32c32-mix-1.0-diffusers) | [`mit-han-lab/dc-ae-f32c32-mix-1.0`](https://huggingface.co/mit-han-lab/dc-ae-f32c32-mix-1.0) +| [`mit-han-lab/dc-ae-f64c128-in-1.0-diffusers`](https://huggingface.co/mit-han-lab/dc-ae-f64c128-in-1.0-diffusers) | [`mit-han-lab/dc-ae-f64c128-in-1.0`](https://huggingface.co/mit-han-lab/dc-ae-f64c128-in-1.0) +| [`mit-han-lab/dc-ae-f64c128-mix-1.0-diffusers`](https://huggingface.co/mit-han-lab/dc-ae-f64c128-mix-1.0-diffusers) | [`mit-han-lab/dc-ae-f64c128-mix-1.0`](https://huggingface.co/mit-han-lab/dc-ae-f64c128-mix-1.0) +| [`mit-han-lab/dc-ae-f128c512-in-1.0-diffusers`](https://huggingface.co/mit-han-lab/dc-ae-f128c512-in-1.0-diffusers) | [`mit-han-lab/dc-ae-f128c512-in-1.0`](https://huggingface.co/mit-han-lab/dc-ae-f128c512-in-1.0) +| [`mit-han-lab/dc-ae-f128c512-mix-1.0-diffusers`](https://huggingface.co/mit-han-lab/dc-ae-f128c512-mix-1.0-diffusers) | [`mit-han-lab/dc-ae-f128c512-mix-1.0`](https://huggingface.co/mit-han-lab/dc-ae-f128c512-mix-1.0) + +This model was contributed by [lawrence-cj](https://github.com/lawrence-cj). + +Load a model in Diffusers format with [`~ModelMixin.from_pretrained`]. + +```python +from diffusers import AutoencoderDC + +ae = AutoencoderDC.from_pretrained("mit-han-lab/dc-ae-f32c32-sana-1.0-diffusers", torch_dtype=torch.float32).to("cuda") +``` + +## Load a model in Diffusers via `from_single_file` + +```python +from difusers import AutoencoderDC + +ckpt_path = "https://huggingface.co/mit-han-lab/dc-ae-f32c32-sana-1.0/blob/main/model.safetensors" +model = AutoencoderDC.from_single_file(ckpt_path) + +``` + +The `AutoencoderDC` model has `in` and `mix` single file checkpoint variants that have matching checkpoint keys, but use different scaling factors. It is not possible for Diffusers to automatically infer the correct config file to use with the model based on just the checkpoint and will default to configuring the model using the `mix` variant config file. To override the automatically determined config, please use the `config` argument when using single file loading with `in` variant checkpoints. + +```python +from diffusers import AutoencoderDC + +ckpt_path = "https://huggingface.co/mit-han-lab/dc-ae-f128c512-in-1.0/blob/main/model.safetensors" +model = AutoencoderDC.from_single_file(ckpt_path, config="mit-han-lab/dc-ae-f128c512-in-1.0-diffusers") +``` + + +## AutoencoderDC + +[[autodoc]] AutoencoderDC + - encode + - decode + - all + +## DecoderOutput + +[[autodoc]] models.autoencoders.vae.DecoderOutput + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_kl_hunyuan_video.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_kl_hunyuan_video.md new file mode 100644 index 0000000000000000000000000000000000000000..33dff5b903cde3f7666c2932467249a64064abc0 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_kl_hunyuan_video.md @@ -0,0 +1,32 @@ + + +# AutoencoderKLHunyuanVideo + +The 3D variational autoencoder (VAE) model with KL loss used in [HunyuanVideo](https://github.com/Tencent/HunyuanVideo/), which was introduced in [HunyuanVideo: A Systematic Framework For Large Video Generative Models](https://huggingface.co/papers/2412.03603) by Tencent. + +The model can be loaded with the following code snippet. + +```python +from diffusers import AutoencoderKLHunyuanVideo + +vae = AutoencoderKLHunyuanVideo.from_pretrained("hunyuanvideo-community/HunyuanVideo", subfolder="vae", torch_dtype=torch.float16) +``` + +## AutoencoderKLHunyuanVideo + +[[autodoc]] AutoencoderKLHunyuanVideo + - decode + - all + +## DecoderOutput + +[[autodoc]] models.autoencoders.vae.DecoderOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_kl_wan.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_kl_wan.md new file mode 100644 index 0000000000000000000000000000000000000000..43165c8edf7a94d7c05e0c2f30b1ae5a0966d056 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_kl_wan.md @@ -0,0 +1,32 @@ + + +# AutoencoderKLWan + +The 3D variational autoencoder (VAE) model with KL loss used in [Wan 2.1](https://github.com/Wan-Video/Wan2.1) by the Alibaba Wan Team. + +The model can be loaded with the following code snippet. + +```python +from diffusers import AutoencoderKLWan + +vae = AutoencoderKLWan.from_pretrained("Wan-AI/Wan2.1-T2V-1.3B-Diffusers", subfolder="vae", torch_dtype=torch.float32) +``` + +## AutoencoderKLWan + +[[autodoc]] AutoencoderKLWan + - decode + - all + +## DecoderOutput + +[[autodoc]] models.autoencoders.vae.DecoderOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_oobleck.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_oobleck.md new file mode 100644 index 0000000000000000000000000000000000000000..bbc00e048b64e19bc4654bd450fd4076e24db10f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_oobleck.md @@ -0,0 +1,38 @@ + + +# AutoencoderOobleck + +The Oobleck variational autoencoder (VAE) model with KL loss was introduced in [Stability-AI/stable-audio-tools](https://github.com/Stability-AI/stable-audio-tools) and [Stable Audio Open](https://huggingface.co/papers/2407.14358) by Stability AI. The model is used in 🤗 Diffusers to encode audio waveforms into latents and to decode latent representations into audio waveforms. + +The abstract from the paper is: + +*Open generative models are vitally important for the community, allowing for fine-tunes and serving as baselines when presenting new models. However, most current text-to-audio models are private and not accessible for artists and researchers to build upon. Here we describe the architecture and training process of a new open-weights text-to-audio model trained with Creative Commons data. Our evaluation shows that the model's performance is competitive with the state-of-the-art across various metrics. Notably, the reported FDopenl3 results (measuring the realism of the generations) showcase its potential for high-quality stereo sound synthesis at 44.1kHz.* + +## AutoencoderOobleck + +[[autodoc]] AutoencoderOobleck + - decode + - encode + - all + +## OobleckDecoderOutput + +[[autodoc]] models.autoencoders.autoencoder_oobleck.OobleckDecoderOutput + +## OobleckDecoderOutput + +[[autodoc]] models.autoencoders.autoencoder_oobleck.OobleckDecoderOutput + +## AutoencoderOobleckOutput + +[[autodoc]] models.autoencoders.autoencoder_oobleck.AutoencoderOobleckOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_tiny.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_tiny.md new file mode 100644 index 0000000000000000000000000000000000000000..25fe2b7a8ab9be7f37e585e27c13365c369878b2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoder_tiny.md @@ -0,0 +1,57 @@ + + +# Tiny AutoEncoder + +Tiny AutoEncoder for Stable Diffusion (TAESD) was introduced in [madebyollin/taesd](https://github.com/madebyollin/taesd) by Ollin Boer Bohan. It is a tiny distilled version of Stable Diffusion's VAE that can quickly decode the latents in a [`StableDiffusionPipeline`] or [`StableDiffusionXLPipeline`] almost instantly. + +To use with Stable Diffusion v-2.1: + +```python +import torch +from diffusers import DiffusionPipeline, AutoencoderTiny + +pipe = DiffusionPipeline.from_pretrained( + "stabilityai/stable-diffusion-2-1-base", torch_dtype=torch.float16 +) +pipe.vae = AutoencoderTiny.from_pretrained("madebyollin/taesd", torch_dtype=torch.float16) +pipe = pipe.to("cuda") + +prompt = "slice of delicious New York-style berry cheesecake" +image = pipe(prompt, num_inference_steps=25).images[0] +image +``` + +To use with Stable Diffusion XL 1.0 + +```python +import torch +from diffusers import DiffusionPipeline, AutoencoderTiny + +pipe = DiffusionPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16 +) +pipe.vae = AutoencoderTiny.from_pretrained("madebyollin/taesdxl", torch_dtype=torch.float16) +pipe = pipe.to("cuda") + +prompt = "slice of delicious New York-style berry cheesecake" +image = pipe(prompt, num_inference_steps=25).images[0] +image +``` + +## AutoencoderTiny + +[[autodoc]] AutoencoderTiny + +## AutoencoderTinyOutput + +[[autodoc]] models.autoencoders.autoencoder_tiny.AutoencoderTinyOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl.md new file mode 100644 index 0000000000000000000000000000000000000000..45b072babc63c53fbd0a894271d7adbc3b30bf6f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl.md @@ -0,0 +1,58 @@ + + +# AutoencoderKL + +The variational autoencoder (VAE) model with KL loss was introduced in [Auto-Encoding Variational Bayes](https://huggingface.co/papers/1312.6114v11) by Diederik P. Kingma and Max Welling. The model is used in 🤗 Diffusers to encode images into latents and to decode latent representations into images. + +The abstract from the paper is: + +*How can we perform efficient inference and learning in directed probabilistic models, in the presence of continuous latent variables with intractable posterior distributions, and large datasets? We introduce a stochastic variational inference and learning algorithm that scales to large datasets and, under some mild differentiability conditions, even works in the intractable case. Our contributions are two-fold. First, we show that a reparameterization of the variational lower bound yields a lower bound estimator that can be straightforwardly optimized using standard stochastic gradient methods. Second, we show that for i.i.d. datasets with continuous latent variables per datapoint, posterior inference can be made especially efficient by fitting an approximate inference model (also called a recognition model) to the intractable posterior using the proposed lower bound estimator. Theoretical advantages are reflected in experimental results.* + +## Loading from the original format + +By default the [`AutoencoderKL`] should be loaded with [`~ModelMixin.from_pretrained`], but it can also be loaded +from the original format using [`FromOriginalModelMixin.from_single_file`] as follows: + +```py +from diffusers import AutoencoderKL + +url = "https://huggingface.co/stabilityai/sd-vae-ft-mse-original/blob/main/vae-ft-mse-840000-ema-pruned.safetensors" # can also be a local file +model = AutoencoderKL.from_single_file(url) +``` + +## AutoencoderKL + +[[autodoc]] AutoencoderKL + - decode + - encode + - all + +## AutoencoderKLOutput + +[[autodoc]] models.autoencoders.autoencoder_kl.AutoencoderKLOutput + +## DecoderOutput + +[[autodoc]] models.autoencoders.vae.DecoderOutput + +## FlaxAutoencoderKL + +[[autodoc]] FlaxAutoencoderKL + +## FlaxAutoencoderKLOutput + +[[autodoc]] models.vae_flax.FlaxAutoencoderKLOutput + +## FlaxDecoderOutput + +[[autodoc]] models.vae_flax.FlaxDecoderOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_allegro.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_allegro.md new file mode 100644 index 0000000000000000000000000000000000000000..83250cd317986765750b07166aa5d83d90c581a2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_allegro.md @@ -0,0 +1,37 @@ + + +# AutoencoderKLAllegro + +The 3D variational autoencoder (VAE) model with KL loss used in [Allegro](https://github.com/rhymes-ai/Allegro) was introduced in [Allegro: Open the Black Box of Commercial-Level Video Generation Model](https://huggingface.co/papers/2410.15458) by RhymesAI. + +The model can be loaded with the following code snippet. + +```python +from diffusers import AutoencoderKLAllegro + +vae = AutoencoderKLAllegro.from_pretrained("rhymes-ai/Allegro", subfolder="vae", torch_dtype=torch.float32).to("cuda") +``` + +## AutoencoderKLAllegro + +[[autodoc]] AutoencoderKLAllegro + - decode + - encode + - all + +## AutoencoderKLOutput + +[[autodoc]] models.autoencoders.autoencoder_kl.AutoencoderKLOutput + +## DecoderOutput + +[[autodoc]] models.autoencoders.vae.DecoderOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_cogvideox.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_cogvideox.md new file mode 100644 index 0000000000000000000000000000000000000000..122812b31d2e52c763a4f9ad4431d3be00beb98b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_cogvideox.md @@ -0,0 +1,37 @@ + + +# AutoencoderKLCogVideoX + +The 3D variational autoencoder (VAE) model with KL loss used in [CogVideoX](https://github.com/THUDM/CogVideo) was introduced in [CogVideoX: Text-to-Video Diffusion Models with An Expert Transformer](https://github.com/THUDM/CogVideo/blob/main/resources/CogVideoX.pdf) by Tsinghua University & ZhipuAI. + +The model can be loaded with the following code snippet. + +```python +from diffusers import AutoencoderKLCogVideoX + +vae = AutoencoderKLCogVideoX.from_pretrained("THUDM/CogVideoX-2b", subfolder="vae", torch_dtype=torch.float16).to("cuda") +``` + +## AutoencoderKLCogVideoX + +[[autodoc]] AutoencoderKLCogVideoX + - decode + - encode + - all + +## AutoencoderKLOutput + +[[autodoc]] models.autoencoders.autoencoder_kl.AutoencoderKLOutput + +## DecoderOutput + +[[autodoc]] models.autoencoders.vae.DecoderOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_cosmos.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_cosmos.md new file mode 100644 index 0000000000000000000000000000000000000000..ed4cd3241c3eff12be79831f929bef120d75fa1b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_cosmos.md @@ -0,0 +1,40 @@ + + +# AutoencoderKLCosmos + +[Cosmos Tokenizers](https://github.com/NVIDIA/Cosmos-Tokenizer). + +Supported models: +- [nvidia/Cosmos-1.0-Tokenizer-CV8x8x8](https://huggingface.co/nvidia/Cosmos-1.0-Tokenizer-CV8x8x8) + +The model can be loaded with the following code snippet. + +```python +from diffusers import AutoencoderKLCosmos + +vae = AutoencoderKLCosmos.from_pretrained("nvidia/Cosmos-1.0-Tokenizer-CV8x8x8", subfolder="vae") +``` + +## AutoencoderKLCosmos + +[[autodoc]] AutoencoderKLCosmos + - decode + - encode + - all + +## AutoencoderKLOutput + +[[autodoc]] models.autoencoders.autoencoder_kl.AutoencoderKLOutput + +## DecoderOutput + +[[autodoc]] models.autoencoders.vae.DecoderOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_ltx_video.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_ltx_video.md new file mode 100644 index 0000000000000000000000000000000000000000..fbdb11e29cdded9f300c111dab2fc2e380148e81 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_ltx_video.md @@ -0,0 +1,37 @@ + + +# AutoencoderKLLTXVideo + +The 3D variational autoencoder (VAE) model with KL loss used in [LTX](https://huggingface.co/Lightricks/LTX-Video) was introduced by Lightricks. + +The model can be loaded with the following code snippet. + +```python +from diffusers import AutoencoderKLLTXVideo + +vae = AutoencoderKLLTXVideo.from_pretrained("Lightricks/LTX-Video", subfolder="vae", torch_dtype=torch.float32).to("cuda") +``` + +## AutoencoderKLLTXVideo + +[[autodoc]] AutoencoderKLLTXVideo + - decode + - encode + - all + +## AutoencoderKLOutput + +[[autodoc]] models.autoencoders.autoencoder_kl.AutoencoderKLOutput + +## DecoderOutput + +[[autodoc]] models.autoencoders.vae.DecoderOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_magvit.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_magvit.md new file mode 100644 index 0000000000000000000000000000000000000000..7c1060ddd435aaeff0058b962bf67bd930a8eac8 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_magvit.md @@ -0,0 +1,37 @@ + + +# AutoencoderKLMagvit + +The 3D variational autoencoder (VAE) model with KL loss used in [EasyAnimate](https://github.com/aigc-apps/EasyAnimate) was introduced by Alibaba PAI. + +The model can be loaded with the following code snippet. + +```python +from diffusers import AutoencoderKLMagvit + +vae = AutoencoderKLMagvit.from_pretrained("alibaba-pai/EasyAnimateV5.1-12b-zh", subfolder="vae", torch_dtype=torch.float16).to("cuda") +``` + +## AutoencoderKLMagvit + +[[autodoc]] AutoencoderKLMagvit + - decode + - encode + - all + +## AutoencoderKLOutput + +[[autodoc]] models.autoencoders.autoencoder_kl.AutoencoderKLOutput + +## DecoderOutput + +[[autodoc]] models.autoencoders.vae.DecoderOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_mochi.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_mochi.md new file mode 100644 index 0000000000000000000000000000000000000000..9747de4af93700f12a1a0d10760430ee123558c1 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/autoencoderkl_mochi.md @@ -0,0 +1,32 @@ + + +# AutoencoderKLMochi + +The 3D variational autoencoder (VAE) model with KL loss used in [Mochi](https://github.com/genmoai/models) was introduced in [Mochi 1 Preview](https://huggingface.co/genmo/mochi-1-preview) by Tsinghua University & ZhipuAI. + +The model can be loaded with the following code snippet. + +```python +from diffusers import AutoencoderKLMochi + +vae = AutoencoderKLMochi.from_pretrained("genmo/mochi-1-preview", subfolder="vae", torch_dtype=torch.float32).to("cuda") +``` + +## AutoencoderKLMochi + +[[autodoc]] AutoencoderKLMochi + - decode + - all + +## DecoderOutput + +[[autodoc]] models.autoencoders.vae.DecoderOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/cogvideox_transformer3d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/cogvideox_transformer3d.md new file mode 100644 index 0000000000000000000000000000000000000000..30556ef7be3fc041d43a46f4fe3795d8e5665145 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/cogvideox_transformer3d.md @@ -0,0 +1,30 @@ + + +# CogVideoXTransformer3DModel + +A Diffusion Transformer model for 3D data from [CogVideoX](https://github.com/THUDM/CogVideo) was introduced in [CogVideoX: Text-to-Video Diffusion Models with An Expert Transformer](https://github.com/THUDM/CogVideo/blob/main/resources/CogVideoX.pdf) by Tsinghua University & ZhipuAI. + +The model can be loaded with the following code snippet. + +```python +from diffusers import CogVideoXTransformer3DModel + +transformer = CogVideoXTransformer3DModel.from_pretrained("THUDM/CogVideoX-2b", subfolder="transformer", torch_dtype=torch.float16).to("cuda") +``` + +## CogVideoXTransformer3DModel + +[[autodoc]] CogVideoXTransformer3DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/cogview3plus_transformer2d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/cogview3plus_transformer2d.md new file mode 100644 index 0000000000000000000000000000000000000000..7d022da793147e1a63e3c57487bec4cbb1b76081 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/cogview3plus_transformer2d.md @@ -0,0 +1,30 @@ + + +# CogView3PlusTransformer2DModel + +A Diffusion Transformer model for 2D data from [CogView3Plus](https://github.com/THUDM/CogView3) was introduced in [CogView3: Finer and Faster Text-to-Image Generation via Relay Diffusion](https://huggingface.co/papers/2403.05121) by Tsinghua University & ZhipuAI. + +The model can be loaded with the following code snippet. + +```python +from diffusers import CogView3PlusTransformer2DModel + +transformer = CogView3PlusTransformer2DModel.from_pretrained("THUDM/CogView3Plus-3b", subfolder="transformer", torch_dtype=torch.bfloat16).to("cuda") +``` + +## CogView3PlusTransformer2DModel + +[[autodoc]] CogView3PlusTransformer2DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/cogview4_transformer2d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/cogview4_transformer2d.md new file mode 100644 index 0000000000000000000000000000000000000000..4bf14bdd499122f731bacd52d14288c16f3a7830 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/cogview4_transformer2d.md @@ -0,0 +1,30 @@ + + +# CogView4Transformer2DModel + +A Diffusion Transformer model for 2D data from [CogView4]() + +The model can be loaded with the following code snippet. + +```python +from diffusers import CogView4Transformer2DModel + +transformer = CogView4Transformer2DModel.from_pretrained("THUDM/CogView4-6B", subfolder="transformer", torch_dtype=torch.bfloat16).to("cuda") +``` + +## CogView4Transformer2DModel + +[[autodoc]] CogView4Transformer2DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/consisid_transformer3d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/consisid_transformer3d.md new file mode 100644 index 0000000000000000000000000000000000000000..2f94033f7fc0abfebc2743535f3b0154f5af92d8 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/consisid_transformer3d.md @@ -0,0 +1,30 @@ + + +# ConsisIDTransformer3DModel + +A Diffusion Transformer model for 3D data from [ConsisID](https://github.com/PKU-YuanGroup/ConsisID) was introduced in [Identity-Preserving Text-to-Video Generation by Frequency Decomposition](https://huggingface.co/papers/2411.17440) by Peking University & University of Rochester & etc. + +The model can be loaded with the following code snippet. + +```python +from diffusers import ConsisIDTransformer3DModel + +transformer = ConsisIDTransformer3DModel.from_pretrained("BestWishYsh/ConsisID-preview", subfolder="transformer", torch_dtype=torch.bfloat16).to("cuda") +``` + +## ConsisIDTransformer3DModel + +[[autodoc]] ConsisIDTransformer3DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/consistency_decoder_vae.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/consistency_decoder_vae.md new file mode 100644 index 0000000000000000000000000000000000000000..94a64820ebb19bc83aad1fbd49914ce9aaad3f1d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/consistency_decoder_vae.md @@ -0,0 +1,30 @@ + + +# Consistency Decoder + +Consistency decoder can be used to decode the latents from the denoising UNet in the [`StableDiffusionPipeline`]. This decoder was introduced in the [DALL-E 3 technical report](https://openai.com/dall-e-3). + +The original codebase can be found at [openai/consistencydecoder](https://github.com/openai/consistencydecoder). + + + +Inference is only supported for 2 iterations as of now. + + + +The pipeline could not have been contributed without the help of [madebyollin](https://github.com/madebyollin) and [mrsteyk](https://github.com/mrsteyk) from [this issue](https://github.com/openai/consistencydecoder/issues/1). + +## ConsistencyDecoderVAE +[[autodoc]] ConsistencyDecoderVAE + - all + - decode diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet.md new file mode 100644 index 0000000000000000000000000000000000000000..5d4cac6658ccfbe3a36e2420ded010a9abe8f290 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet.md @@ -0,0 +1,50 @@ + + +# ControlNetModel + +The ControlNet model was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, Maneesh Agrawala. It provides a greater degree of control over text-to-image generation by conditioning the model on additional inputs such as edge maps, depth maps, segmentation maps, and keypoints for pose detection. + +The abstract from the paper is: + +*We present ControlNet, a neural network architecture to add spatial conditioning controls to large, pretrained text-to-image diffusion models. ControlNet locks the production-ready large diffusion models, and reuses their deep and robust encoding layers pretrained with billions of images as a strong backbone to learn a diverse set of conditional controls. The neural architecture is connected with "zero convolutions" (zero-initialized convolution layers) that progressively grow the parameters from zero and ensure that no harmful noise could affect the finetuning. We test various conditioning controls, eg, edges, depth, segmentation, human pose, etc, with Stable Diffusion, using single or multiple conditions, with or without prompts. We show that the training of ControlNets is robust with small (<50k) and large (>1m) datasets. Extensive results show that ControlNet may facilitate wider applications to control image diffusion models.* + +## Loading from the original format + +By default the [`ControlNetModel`] should be loaded with [`~ModelMixin.from_pretrained`], but it can also be loaded +from the original format using [`FromOriginalModelMixin.from_single_file`] as follows: + +```py +from diffusers import StableDiffusionControlNetPipeline, ControlNetModel + +url = "https://huggingface.co/lllyasviel/ControlNet-v1-1/blob/main/control_v11p_sd15_canny.pth" # can also be a local path +controlnet = ControlNetModel.from_single_file(url) + +url = "https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5/blob/main/v1-5-pruned.safetensors" # can also be a local path +pipe = StableDiffusionControlNetPipeline.from_single_file(url, controlnet=controlnet) +``` + +## ControlNetModel + +[[autodoc]] ControlNetModel + +## ControlNetOutput + +[[autodoc]] models.controlnets.controlnet.ControlNetOutput + +## FlaxControlNetModel + +[[autodoc]] FlaxControlNetModel + +## FlaxControlNetOutput + +[[autodoc]] models.controlnets.controlnet_flax.FlaxControlNetOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_flux.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_flux.md new file mode 100644 index 0000000000000000000000000000000000000000..422d066d95ff2c6e1792c8026cfb2cd3ae9d4ec9 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_flux.md @@ -0,0 +1,45 @@ + + +# FluxControlNetModel + +FluxControlNetModel is an implementation of ControlNet for Flux.1. + +The ControlNet model was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, Maneesh Agrawala. It provides a greater degree of control over text-to-image generation by conditioning the model on additional inputs such as edge maps, depth maps, segmentation maps, and keypoints for pose detection. + +The abstract from the paper is: + +*We present ControlNet, a neural network architecture to add spatial conditioning controls to large, pretrained text-to-image diffusion models. ControlNet locks the production-ready large diffusion models, and reuses their deep and robust encoding layers pretrained with billions of images as a strong backbone to learn a diverse set of conditional controls. The neural architecture is connected with "zero convolutions" (zero-initialized convolution layers) that progressively grow the parameters from zero and ensure that no harmful noise could affect the finetuning. We test various conditioning controls, eg, edges, depth, segmentation, human pose, etc, with Stable Diffusion, using single or multiple conditions, with or without prompts. We show that the training of ControlNets is robust with small (<50k) and large (>1m) datasets. Extensive results show that ControlNet may facilitate wider applications to control image diffusion models.* + +## Loading from the original format + +By default the [`FluxControlNetModel`] should be loaded with [`~ModelMixin.from_pretrained`]. + +```py +from diffusers import FluxControlNetPipeline +from diffusers.models import FluxControlNetModel, FluxMultiControlNetModel + +controlnet = FluxControlNetModel.from_pretrained("InstantX/FLUX.1-dev-Controlnet-Canny") +pipe = FluxControlNetPipeline.from_pretrained("black-forest-labs/FLUX.1-dev", controlnet=controlnet) + +controlnet = FluxControlNetModel.from_pretrained("InstantX/FLUX.1-dev-Controlnet-Canny") +controlnet = FluxMultiControlNetModel([controlnet]) +pipe = FluxControlNetPipeline.from_pretrained("black-forest-labs/FLUX.1-dev", controlnet=controlnet) +``` + +## FluxControlNetModel + +[[autodoc]] FluxControlNetModel + +## FluxControlNetOutput + +[[autodoc]] models.controlnet_flux.FluxControlNetOutput \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_hunyuandit.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_hunyuandit.md new file mode 100644 index 0000000000000000000000000000000000000000..9b8f186c8d2cb732f22efc2ea265f7fa4e014753 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_hunyuandit.md @@ -0,0 +1,37 @@ + + +# HunyuanDiT2DControlNetModel + +HunyuanDiT2DControlNetModel is an implementation of ControlNet for [Hunyuan-DiT](https://huggingface.co/papers/2405.08748). + +ControlNet was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, and Maneesh Agrawala. + +With a ControlNet model, you can provide an additional control image to condition and control Hunyuan-DiT generation. For example, if you provide a depth map, the ControlNet model generates an image that'll preserve the spatial information from the depth map. It is a more flexible and accurate way to control the image generation process. + +The abstract from the paper is: + +*We present ControlNet, a neural network architecture to add spatial conditioning controls to large, pretrained text-to-image diffusion models. ControlNet locks the production-ready large diffusion models, and reuses their deep and robust encoding layers pretrained with billions of images as a strong backbone to learn a diverse set of conditional controls. The neural architecture is connected with "zero convolutions" (zero-initialized convolution layers) that progressively grow the parameters from zero and ensure that no harmful noise could affect the finetuning. We test various conditioning controls, eg, edges, depth, segmentation, human pose, etc, with Stable Diffusion, using single or multiple conditions, with or without prompts. We show that the training of ControlNets is robust with small (<50k) and large (>1m) datasets. Extensive results show that ControlNet may facilitate wider applications to control image diffusion models.* + +This code is implemented by Tencent Hunyuan Team. You can find pre-trained checkpoints for Hunyuan-DiT ControlNets on [Tencent Hunyuan](https://huggingface.co/Tencent-Hunyuan). + +## Example For Loading HunyuanDiT2DControlNetModel + +```py +from diffusers import HunyuanDiT2DControlNetModel +import torch +controlnet = HunyuanDiT2DControlNetModel.from_pretrained("Tencent-Hunyuan/HunyuanDiT-v1.1-ControlNet-Diffusers-Pose", torch_dtype=torch.float16) +``` + +## HunyuanDiT2DControlNetModel + +[[autodoc]] HunyuanDiT2DControlNetModel \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_sana.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_sana.md new file mode 100644 index 0000000000000000000000000000000000000000..f0426308f7e02a8b42f45220a36e7472fe90fa4f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_sana.md @@ -0,0 +1,29 @@ + + +# SanaControlNetModel + +The ControlNet model was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, Maneesh Agrawala. It provides a greater degree of control over text-to-image generation by conditioning the model on additional inputs such as edge maps, depth maps, segmentation maps, and keypoints for pose detection. + +The abstract from the paper is: + +*We present ControlNet, a neural network architecture to add spatial conditioning controls to large, pretrained text-to-image diffusion models. ControlNet locks the production-ready large diffusion models, and reuses their deep and robust encoding layers pretrained with billions of images as a strong backbone to learn a diverse set of conditional controls. The neural architecture is connected with "zero convolutions" (zero-initialized convolution layers) that progressively grow the parameters from zero and ensure that no harmful noise could affect the finetuning. We test various conditioning controls, eg, edges, depth, segmentation, human pose, etc, with Stable Diffusion, using single or multiple conditions, with or without prompts. We show that the training of ControlNets is robust with small (<50k) and large (>1m) datasets. Extensive results show that ControlNet may facilitate wider applications to control image diffusion models.* + +This model was contributed by [ishan24](https://huggingface.co/ishan24). ❤️ +The original codebase can be found at [NVlabs/Sana](https://github.com/NVlabs/Sana), and you can find official ControlNet checkpoints on [Efficient-Large-Model's](https://huggingface.co/Efficient-Large-Model) Hub profile. + +## SanaControlNetModel +[[autodoc]] SanaControlNetModel + +## SanaControlNetOutput +[[autodoc]] models.controlnets.controlnet_sana.SanaControlNetOutput + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_sd3.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_sd3.md new file mode 100644 index 0000000000000000000000000000000000000000..78564d238eea1be753f21b1c5a41f615a4e872dc --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_sd3.md @@ -0,0 +1,42 @@ + + +# SD3ControlNetModel + +SD3ControlNetModel is an implementation of ControlNet for Stable Diffusion 3. + +The ControlNet model was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, Maneesh Agrawala. It provides a greater degree of control over text-to-image generation by conditioning the model on additional inputs such as edge maps, depth maps, segmentation maps, and keypoints for pose detection. + +The abstract from the paper is: + +*We present ControlNet, a neural network architecture to add spatial conditioning controls to large, pretrained text-to-image diffusion models. ControlNet locks the production-ready large diffusion models, and reuses their deep and robust encoding layers pretrained with billions of images as a strong backbone to learn a diverse set of conditional controls. The neural architecture is connected with "zero convolutions" (zero-initialized convolution layers) that progressively grow the parameters from zero and ensure that no harmful noise could affect the finetuning. We test various conditioning controls, eg, edges, depth, segmentation, human pose, etc, with Stable Diffusion, using single or multiple conditions, with or without prompts. We show that the training of ControlNets is robust with small (<50k) and large (>1m) datasets. Extensive results show that ControlNet may facilitate wider applications to control image diffusion models.* + +## Loading from the original format + +By default the [`SD3ControlNetModel`] should be loaded with [`~ModelMixin.from_pretrained`]. + +```py +from diffusers import StableDiffusion3ControlNetPipeline +from diffusers.models import SD3ControlNetModel, SD3MultiControlNetModel + +controlnet = SD3ControlNetModel.from_pretrained("InstantX/SD3-Controlnet-Canny") +pipe = StableDiffusion3ControlNetPipeline.from_pretrained("stabilityai/stable-diffusion-3-medium-diffusers", controlnet=controlnet) +``` + +## SD3ControlNetModel + +[[autodoc]] SD3ControlNetModel + +## SD3ControlNetOutput + +[[autodoc]] models.controlnets.controlnet_sd3.SD3ControlNetOutput + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_sparsectrl.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_sparsectrl.md new file mode 100644 index 0000000000000000000000000000000000000000..e15d80ee3982cdad49c02bd5dce29cd5d3064b42 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_sparsectrl.md @@ -0,0 +1,46 @@ + + +# SparseControlNetModel + +SparseControlNetModel is an implementation of ControlNet for [AnimateDiff](https://huggingface.co/papers/2307.04725). + +ControlNet was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, and Maneesh Agrawala. + +The SparseCtrl version of ControlNet was introduced in [SparseCtrl: Adding Sparse Controls to Text-to-Video Diffusion Models](https://huggingface.co/papers/2311.16933) for achieving controlled generation in text-to-video diffusion models by Yuwei Guo, Ceyuan Yang, Anyi Rao, Maneesh Agrawala, Dahua Lin, and Bo Dai. + +The abstract from the paper is: + +*The development of text-to-video (T2V), i.e., generating videos with a given text prompt, has been significantly advanced in recent years. However, relying solely on text prompts often results in ambiguous frame composition due to spatial uncertainty. The research community thus leverages the dense structure signals, e.g., per-frame depth/edge sequences, to enhance controllability, whose collection accordingly increases the burden of inference. In this work, we present SparseCtrl to enable flexible structure control with temporally sparse signals, requiring only one or a few inputs, as shown in Figure 1. It incorporates an additional condition encoder to process these sparse signals while leaving the pre-trained T2V model untouched. The proposed approach is compatible with various modalities, including sketches, depth maps, and RGB images, providing more practical control for video generation and promoting applications such as storyboarding, depth rendering, keyframe animation, and interpolation. Extensive experiments demonstrate the generalization of SparseCtrl on both original and personalized T2V generators. Codes and models will be publicly available at [this https URL](https://guoyww.github.io/projects/SparseCtrl).* + +## Example for loading SparseControlNetModel + +```python +import torch +from diffusers import SparseControlNetModel + +# fp32 variant in float16 +# 1. Scribble checkpoint +controlnet = SparseControlNetModel.from_pretrained("guoyww/animatediff-sparsectrl-scribble", torch_dtype=torch.float16) + +# 2. RGB checkpoint +controlnet = SparseControlNetModel.from_pretrained("guoyww/animatediff-sparsectrl-rgb", torch_dtype=torch.float16) + +# For loading fp16 variant, pass `variant="fp16"` as an additional parameter +``` + +## SparseControlNetModel + +[[autodoc]] SparseControlNetModel + +## SparseControlNetOutput + +[[autodoc]] models.controlnet_sparsectrl.SparseControlNetOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_union.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_union.md new file mode 100644 index 0000000000000000000000000000000000000000..9c0d86984549513ead2cf7f8ec71f97340224b0b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/controlnet_union.md @@ -0,0 +1,35 @@ + + +# ControlNetUnionModel + +ControlNetUnionModel is an implementation of ControlNet for Stable Diffusion XL. + +The ControlNet model was introduced in [ControlNetPlus](https://github.com/xinsir6/ControlNetPlus) by xinsir6. It supports multiple conditioning inputs without increasing computation. + +*We design a new architecture that can support 10+ control types in condition text-to-image generation and can generate high resolution images visually comparable with midjourney. The network is based on the original ControlNet architecture, we propose two new modules to: 1 Extend the original ControlNet to support different image conditions using the same network parameter. 2 Support multiple conditions input without increasing computation offload, which is especially important for designers who want to edit image in detail, different conditions use the same condition encoder, without adding extra computations or parameters.* + +## Loading + +By default the [`ControlNetUnionModel`] should be loaded with [`~ModelMixin.from_pretrained`]. + +```py +from diffusers import StableDiffusionXLControlNetUnionPipeline, ControlNetUnionModel + +controlnet = ControlNetUnionModel.from_pretrained("xinsir/controlnet-union-sdxl-1.0") +pipe = StableDiffusionXLControlNetUnionPipeline.from_pretrained("stabilityai/stable-diffusion-xl-base-1.0", controlnet=controlnet) +``` + +## ControlNetUnionModel + +[[autodoc]] ControlNetUnionModel + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/cosmos_transformer3d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/cosmos_transformer3d.md new file mode 100644 index 0000000000000000000000000000000000000000..e4063396edbd3d2913146d4d4fb75eb528999132 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/cosmos_transformer3d.md @@ -0,0 +1,30 @@ + + +# CosmosTransformer3DModel + +A Diffusion Transformer model for 3D video-like data was introduced in [Cosmos World Foundation Model Platform for Physical AI](https://huggingface.co/papers/2501.03575) by NVIDIA. + +The model can be loaded with the following code snippet. + +```python +from diffusers import CosmosTransformer3DModel + +transformer = CosmosTransformer3DModel.from_pretrained("nvidia/Cosmos-1.0-Diffusion-7B-Text2World", subfolder="transformer", torch_dtype=torch.bfloat16) +``` + +## CosmosTransformer3DModel + +[[autodoc]] CosmosTransformer3DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/dit_transformer2d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/dit_transformer2d.md new file mode 100644 index 0000000000000000000000000000000000000000..afac62d53cb453202465fbf62fc1d07080009505 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/dit_transformer2d.md @@ -0,0 +1,19 @@ + + +# DiTTransformer2DModel + +A Transformer model for image-like data from [DiT](https://huggingface.co/papers/2212.09748). + +## DiTTransformer2DModel + +[[autodoc]] DiTTransformer2DModel diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/easyanimate_transformer3d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/easyanimate_transformer3d.md new file mode 100644 index 0000000000000000000000000000000000000000..66670eb632d400849643421371a720d261c0dfc0 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/easyanimate_transformer3d.md @@ -0,0 +1,30 @@ + + +# EasyAnimateTransformer3DModel + +A Diffusion Transformer model for 3D data from [EasyAnimate](https://github.com/aigc-apps/EasyAnimate) was introduced by Alibaba PAI. + +The model can be loaded with the following code snippet. + +```python +from diffusers import EasyAnimateTransformer3DModel + +transformer = EasyAnimateTransformer3DModel.from_pretrained("alibaba-pai/EasyAnimateV5.1-12b-zh", subfolder="transformer", torch_dtype=torch.float16).to("cuda") +``` + +## EasyAnimateTransformer3DModel + +[[autodoc]] EasyAnimateTransformer3DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/flux_transformer.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/flux_transformer.md new file mode 100644 index 0000000000000000000000000000000000000000..381593f1bfe6c121bc6a4ee51f84a04fb8e4a8c4 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/flux_transformer.md @@ -0,0 +1,19 @@ + + +# FluxTransformer2DModel + +A Transformer model for image-like data from [Flux](https://blackforestlabs.ai/announcing-black-forest-labs/). + +## FluxTransformer2DModel + +[[autodoc]] FluxTransformer2DModel diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/hidream_image_transformer.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/hidream_image_transformer.md new file mode 100644 index 0000000000000000000000000000000000000000..5dbf40b5a14c977c903b22bd92da6dd5422538d5 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/hidream_image_transformer.md @@ -0,0 +1,46 @@ + + +# HiDreamImageTransformer2DModel + +A Transformer model for image-like data from [HiDream-I1](https://huggingface.co/HiDream-ai). + +The model can be loaded with the following code snippet. + +```python +from diffusers import HiDreamImageTransformer2DModel + +transformer = HiDreamImageTransformer2DModel.from_pretrained("HiDream-ai/HiDream-I1-Full", subfolder="transformer", torch_dtype=torch.bfloat16) +``` + +## Loading GGUF quantized checkpoints for HiDream-I1 + +GGUF checkpoints for the `HiDreamImageTransformer2DModel` can be loaded using `~FromOriginalModelMixin.from_single_file` + +```python +import torch +from diffusers import GGUFQuantizationConfig, HiDreamImageTransformer2DModel + +ckpt_path = "https://huggingface.co/city96/HiDream-I1-Dev-gguf/blob/main/hidream-i1-dev-Q2_K.gguf" +transformer = HiDreamImageTransformer2DModel.from_single_file( + ckpt_path, + quantization_config=GGUFQuantizationConfig(compute_dtype=torch.bfloat16), + torch_dtype=torch.bfloat16 +) +``` + +## HiDreamImageTransformer2DModel + +[[autodoc]] HiDreamImageTransformer2DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/hunyuan_transformer2d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/hunyuan_transformer2d.md new file mode 100644 index 0000000000000000000000000000000000000000..fe137236d18e02e379bddfda4ce3b938b5a57832 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/hunyuan_transformer2d.md @@ -0,0 +1,20 @@ + + +# HunyuanDiT2DModel + +A Diffusion Transformer model for 2D data from [Hunyuan-DiT](https://github.com/Tencent/HunyuanDiT). + +## HunyuanDiT2DModel + +[[autodoc]] HunyuanDiT2DModel + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/hunyuan_video_transformer_3d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/hunyuan_video_transformer_3d.md new file mode 100644 index 0000000000000000000000000000000000000000..522d0eb0479db7180afedb4586c9d1bac160ccc8 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/hunyuan_video_transformer_3d.md @@ -0,0 +1,30 @@ + + +# HunyuanVideoTransformer3DModel + +A Diffusion Transformer model for 3D video-like data was introduced in [HunyuanVideo: A Systematic Framework For Large Video Generative Models](https://huggingface.co/papers/2412.03603) by Tencent. + +The model can be loaded with the following code snippet. + +```python +from diffusers import HunyuanVideoTransformer3DModel + +transformer = HunyuanVideoTransformer3DModel.from_pretrained("hunyuanvideo-community/HunyuanVideo", subfolder="transformer", torch_dtype=torch.bfloat16) +``` + +## HunyuanVideoTransformer3DModel + +[[autodoc]] HunyuanVideoTransformer3DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/latte_transformer3d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/latte_transformer3d.md new file mode 100644 index 0000000000000000000000000000000000000000..f87926aefc9fca098b5838c59ad54fbddbd3e11c --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/latte_transformer3d.md @@ -0,0 +1,19 @@ + + +## LatteTransformer3DModel + +A Diffusion Transformer model for 3D data from [Latte](https://github.com/Vchitect/Latte). + +## LatteTransformer3DModel + +[[autodoc]] LatteTransformer3DModel diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/ltx_video_transformer3d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/ltx_video_transformer3d.md new file mode 100644 index 0000000000000000000000000000000000000000..fe2664cf685c9b9c0893d535e0980d5ae9b8557a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/ltx_video_transformer3d.md @@ -0,0 +1,30 @@ + + +# LTXVideoTransformer3DModel + +A Diffusion Transformer model for 3D data from [LTX](https://huggingface.co/Lightricks/LTX-Video) was introduced by Lightricks. + +The model can be loaded with the following code snippet. + +```python +from diffusers import LTXVideoTransformer3DModel + +transformer = LTXVideoTransformer3DModel.from_pretrained("Lightricks/LTX-Video", subfolder="transformer", torch_dtype=torch.bfloat16).to("cuda") +``` + +## LTXVideoTransformer3DModel + +[[autodoc]] LTXVideoTransformer3DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/lumina2_transformer2d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/lumina2_transformer2d.md new file mode 100644 index 0000000000000000000000000000000000000000..0d7c0585dcd5a4f1fa2132c92f86f2ba674ed89f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/lumina2_transformer2d.md @@ -0,0 +1,30 @@ + + +# Lumina2Transformer2DModel + +A Diffusion Transformer model for 3D video-like data was introduced in [Lumina Image 2.0](https://huggingface.co/Alpha-VLLM/Lumina-Image-2.0) by Alpha-VLLM. + +The model can be loaded with the following code snippet. + +```python +from diffusers import Lumina2Transformer2DModel + +transformer = Lumina2Transformer2DModel.from_pretrained("Alpha-VLLM/Lumina-Image-2.0", subfolder="transformer", torch_dtype=torch.bfloat16) +``` + +## Lumina2Transformer2DModel + +[[autodoc]] Lumina2Transformer2DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/lumina_nextdit2d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/lumina_nextdit2d.md new file mode 100644 index 0000000000000000000000000000000000000000..fe28918e2b580b3f7a02e43073b6b9bae6a7f6ab --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/lumina_nextdit2d.md @@ -0,0 +1,20 @@ + + +# LuminaNextDiT2DModel + +A Next Version of Diffusion Transformer model for 2D data from [Lumina-T2X](https://github.com/Alpha-VLLM/Lumina-T2X). + +## LuminaNextDiT2DModel + +[[autodoc]] LuminaNextDiT2DModel + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/mochi_transformer3d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/mochi_transformer3d.md new file mode 100644 index 0000000000000000000000000000000000000000..6c8e464feded82da81bb0d629112178ee5604897 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/mochi_transformer3d.md @@ -0,0 +1,30 @@ + + +# MochiTransformer3DModel + +A Diffusion Transformer model for 3D video-like data was introduced in [Mochi-1 Preview](https://huggingface.co/genmo/mochi-1-preview) by Genmo. + +The model can be loaded with the following code snippet. + +```python +from diffusers import MochiTransformer3DModel + +transformer = MochiTransformer3DModel.from_pretrained("genmo/mochi-1-preview", subfolder="transformer", torch_dtype=torch.float16).to("cuda") +``` + +## MochiTransformer3DModel + +[[autodoc]] MochiTransformer3DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/omnigen_transformer.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/omnigen_transformer.md new file mode 100644 index 0000000000000000000000000000000000000000..78d29fdab5e44c9d146ab04b735ebe27dc2c1e0e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/omnigen_transformer.md @@ -0,0 +1,30 @@ + + +# OmniGenTransformer2DModel + +A Transformer model that accepts multimodal instructions to generate images for [OmniGen](https://github.com/VectorSpaceLab/OmniGen/). + +The abstract from the paper is: + +*The emergence of Large Language Models (LLMs) has unified language generation tasks and revolutionized human-machine interaction. However, in the realm of image generation, a unified model capable of handling various tasks within a single framework remains largely unexplored. In this work, we introduce OmniGen, a new diffusion model for unified image generation. OmniGen is characterized by the following features: 1) Unification: OmniGen not only demonstrates text-to-image generation capabilities but also inherently supports various downstream tasks, such as image editing, subject-driven generation, and visual conditional generation. 2) Simplicity: The architecture of OmniGen is highly simplified, eliminating the need for additional plugins. Moreover, compared to existing diffusion models, it is more user-friendly and can complete complex tasks end-to-end through instructions without the need for extra intermediate steps, greatly simplifying the image generation workflow. 3) Knowledge Transfer: Benefit from learning in a unified format, OmniGen effectively transfers knowledge across different tasks, manages unseen tasks and domains, and exhibits novel capabilities. We also explore the model’s reasoning capabilities and potential applications of the chain-of-thought mechanism. This work represents the first attempt at a general-purpose image generation model, and we will release our resources at https://github.com/VectorSpaceLab/OmniGen to foster future advancements.* + +```python +import torch +from diffusers import OmniGenTransformer2DModel + +transformer = OmniGenTransformer2DModel.from_pretrained("Shitao/OmniGen-v1-diffusers", subfolder="transformer", torch_dtype=torch.bfloat16) +``` + +## OmniGenTransformer2DModel + +[[autodoc]] OmniGenTransformer2DModel diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/overview.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/overview.md new file mode 100644 index 0000000000000000000000000000000000000000..62e75f26b5b09adedfbb14e9dd39731059443b11 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/overview.md @@ -0,0 +1,28 @@ + + +# Models + +🤗 Diffusers provides pretrained models for popular algorithms and modules to create custom diffusion systems. The primary function of models is to denoise an input sample as modeled by the distribution \\(p_{\theta}(x_{t-1}|x_{t})\\). + +All models are built from the base [`ModelMixin`] class which is a [`torch.nn.Module`](https://pytorch.org/docs/stable/generated/torch.nn.Module.html) providing basic functionality for saving and loading models, locally and from the Hugging Face Hub. + +## ModelMixin +[[autodoc]] ModelMixin + +## FlaxModelMixin + +[[autodoc]] FlaxModelMixin + +## PushToHubMixin + +[[autodoc]] utils.PushToHubMixin diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/pixart_transformer2d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/pixart_transformer2d.md new file mode 100644 index 0000000000000000000000000000000000000000..1d392f4e7c2c3cf37878d38f6fd3e6797cb44db7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/pixart_transformer2d.md @@ -0,0 +1,19 @@ + + +# PixArtTransformer2DModel + +A Transformer model for image-like data from [PixArt-Alpha](https://huggingface.co/papers/2310.00426) and [PixArt-Sigma](https://huggingface.co/papers/2403.04692). + +## PixArtTransformer2DModel + +[[autodoc]] PixArtTransformer2DModel diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/prior_transformer.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/prior_transformer.md new file mode 100644 index 0000000000000000000000000000000000000000..3d4e3a81782c78c62932403fefe58f2c3a5bad28 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/prior_transformer.md @@ -0,0 +1,27 @@ + + +# PriorTransformer + +The Prior Transformer was originally introduced in [Hierarchical Text-Conditional Image Generation with CLIP Latents](https://huggingface.co/papers/2204.06125) by Ramesh et al. It is used to predict CLIP image embeddings from CLIP text embeddings; image embeddings are predicted through a denoising diffusion process. + +The abstract from the paper is: + +*Contrastive models like CLIP have been shown to learn robust representations of images that capture both semantics and style. To leverage these representations for image generation, we propose a two-stage model: a prior that generates a CLIP image embedding given a text caption, and a decoder that generates an image conditioned on the image embedding. We show that explicitly generating image representations improves image diversity with minimal loss in photorealism and caption similarity. Our decoders conditioned on image representations can also produce variations of an image that preserve both its semantics and style, while varying the non-essential details absent from the image representation. Moreover, the joint embedding space of CLIP enables language-guided image manipulations in a zero-shot fashion. We use diffusion models for the decoder and experiment with both autoregressive and diffusion models for the prior, finding that the latter are computationally more efficient and produce higher-quality samples.* + +## PriorTransformer + +[[autodoc]] PriorTransformer + +## PriorTransformerOutput + +[[autodoc]] models.transformers.prior_transformer.PriorTransformerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/sana_transformer2d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/sana_transformer2d.md new file mode 100644 index 0000000000000000000000000000000000000000..269aefd7ff699d4cc7671c1e5950c0085670e018 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/sana_transformer2d.md @@ -0,0 +1,34 @@ + + +# SanaTransformer2DModel + +A Diffusion Transformer model for 2D data from [SANA: Efficient High-Resolution Image Synthesis with Linear Diffusion Transformers](https://huggingface.co/papers/2410.10629) was introduced from NVIDIA and MIT HAN Lab, by Enze Xie, Junsong Chen, Junyu Chen, Han Cai, Haotian Tang, Yujun Lin, Zhekai Zhang, Muyang Li, Ligeng Zhu, Yao Lu, Song Han. + +The abstract from the paper is: + +*We introduce Sana, a text-to-image framework that can efficiently generate images up to 4096×4096 resolution. Sana can synthesize high-resolution, high-quality images with strong text-image alignment at a remarkably fast speed, deployable on laptop GPU. Core designs include: (1) Deep compression autoencoder: unlike traditional AEs, which compress images only 8×, we trained an AE that can compress images 32×, effectively reducing the number of latent tokens. (2) Linear DiT: we replace all vanilla attention in DiT with linear attention, which is more efficient at high resolutions without sacrificing quality. (3) Decoder-only text encoder: we replaced T5 with modern decoder-only small LLM as the text encoder and designed complex human instruction with in-context learning to enhance the image-text alignment. (4) Efficient training and sampling: we propose Flow-DPM-Solver to reduce sampling steps, with efficient caption labeling and selection to accelerate convergence. As a result, Sana-0.6B is very competitive with modern giant diffusion model (e.g. Flux-12B), being 20 times smaller and 100+ times faster in measured throughput. Moreover, Sana-0.6B can be deployed on a 16GB laptop GPU, taking less than 1 second to generate a 1024×1024 resolution image. Sana enables content creation at low cost. Code and model will be publicly released.* + +The model can be loaded with the following code snippet. + +```python +from diffusers import SanaTransformer2DModel + +transformer = SanaTransformer2DModel.from_pretrained("Efficient-Large-Model/Sana_1600M_1024px_BF16_diffusers", subfolder="transformer", torch_dtype=torch.bfloat16) +``` + +## SanaTransformer2DModel + +[[autodoc]] SanaTransformer2DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/sd3_transformer2d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/sd3_transformer2d.md new file mode 100644 index 0000000000000000000000000000000000000000..feef87db3a635e5de489e62bd7fbc5dbe3ecffcf --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/sd3_transformer2d.md @@ -0,0 +1,19 @@ + + +# SD3 Transformer Model + +The Transformer model introduced in [Stable Diffusion 3](https://hf.co/papers/2403.03206). Its novelty lies in the MMDiT transformer block. + +## SD3Transformer2DModel + +[[autodoc]] SD3Transformer2DModel \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/stable_audio_transformer.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/stable_audio_transformer.md new file mode 100644 index 0000000000000000000000000000000000000000..396b96c8c710cab9b0cd577614b5c36df0f0f41d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/stable_audio_transformer.md @@ -0,0 +1,19 @@ + + +# StableAudioDiTModel + +A Transformer model for audio waveforms from [Stable Audio Open](https://huggingface.co/papers/2407.14358). + +## StableAudioDiTModel + +[[autodoc]] StableAudioDiTModel diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/stable_cascade_unet.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/stable_cascade_unet.md new file mode 100644 index 0000000000000000000000000000000000000000..31b780079d76359836ec36f38255499995b9edaa --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/stable_cascade_unet.md @@ -0,0 +1,19 @@ + + +# StableCascadeUNet + +A UNet model from the [Stable Cascade pipeline](../pipelines/stable_cascade.md). + +## StableCascadeUNet + +[[autodoc]] models.unets.unet_stable_cascade.StableCascadeUNet diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/transformer2d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/transformer2d.md new file mode 100644 index 0000000000000000000000000000000000000000..077ccbb6b235f25fec4ee0c9f40875b41932a3dd --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/transformer2d.md @@ -0,0 +1,41 @@ + + +# Transformer2DModel + +A Transformer model for image-like data from [CompVis](https://huggingface.co/CompVis) that is based on the [Vision Transformer](https://huggingface.co/papers/2010.11929) introduced by Dosovitskiy et al. The [`Transformer2DModel`] accepts discrete (classes of vector embeddings) or continuous (actual embeddings) inputs. + +When the input is **continuous**: + +1. Project the input and reshape it to `(batch_size, sequence_length, feature_dimension)`. +2. Apply the Transformer blocks in the standard way. +3. Reshape to image. + +When the input is **discrete**: + + + +It is assumed one of the input classes is the masked latent pixel. The predicted classes of the unnoised image don't contain a prediction for the masked pixel because the unnoised image cannot be masked. + + + +1. Convert input (classes of latent pixels) to embeddings and apply positional embeddings. +2. Apply the Transformer blocks in the standard way. +3. Predict classes of unnoised image. + +## Transformer2DModel + +[[autodoc]] Transformer2DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/transformer_temporal.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/transformer_temporal.md new file mode 100644 index 0000000000000000000000000000000000000000..02d075dea3f39a753bf8d6e44b2de624418d8fd5 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/transformer_temporal.md @@ -0,0 +1,23 @@ + + +# TransformerTemporalModel + +A Transformer model for video-like data. + +## TransformerTemporalModel + +[[autodoc]] models.transformers.transformer_temporal.TransformerTemporalModel + +## TransformerTemporalModelOutput + +[[autodoc]] models.transformers.transformer_temporal.TransformerTemporalModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet-motion.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet-motion.md new file mode 100644 index 0000000000000000000000000000000000000000..9396f6477bf1756960d82672bdb115b133223476 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet-motion.md @@ -0,0 +1,25 @@ + + +# UNetMotionModel + +The [UNet](https://huggingface.co/papers/1505.04597) model was originally introduced by Ronneberger et al for biomedical image segmentation, but it is also commonly used in 🤗 Diffusers because it outputs images that are the same size as the input. It is one of the most important components of a diffusion system because it facilitates the actual diffusion process. There are several variants of the UNet model in 🤗 Diffusers, depending on it's number of dimensions and whether it is a conditional model or not. This is a 2D UNet model. + +The abstract from the paper is: + +*There is large consent that successful training of deep networks requires many thousand annotated training samples. In this paper, we present a network and training strategy that relies on the strong use of data augmentation to use the available annotated samples more efficiently. The architecture consists of a contracting path to capture context and a symmetric expanding path that enables precise localization. We show that such a network can be trained end-to-end from very few images and outperforms the prior best method (a sliding-window convolutional network) on the ISBI challenge for segmentation of neuronal structures in electron microscopic stacks. Using the same network trained on transmitted light microscopy images (phase contrast and DIC) we won the ISBI cell tracking challenge 2015 in these categories by a large margin. Moreover, the network is fast. Segmentation of a 512x512 image takes less than a second on a recent GPU. The full implementation (based on Caffe) and the trained networks are available at http://lmb.informatik.uni-freiburg.de/people/ronneber/u-net.* + +## UNetMotionModel +[[autodoc]] UNetMotionModel + +## UNet3DConditionOutput +[[autodoc]] models.unets.unet_3d_condition.UNet3DConditionOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet.md new file mode 100644 index 0000000000000000000000000000000000000000..bf36aae1f6d91c87b2cfe4872ccfdb251bd5c62e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet.md @@ -0,0 +1,25 @@ + + +# UNet1DModel + +The [UNet](https://huggingface.co/papers/1505.04597) model was originally introduced by Ronneberger et al. for biomedical image segmentation, but it is also commonly used in 🤗 Diffusers because it outputs images that are the same size as the input. It is one of the most important components of a diffusion system because it facilitates the actual diffusion process. There are several variants of the UNet model in 🤗 Diffusers, depending on it's number of dimensions and whether it is a conditional model or not. This is a 1D UNet model. + +The abstract from the paper is: + +*There is large consent that successful training of deep networks requires many thousand annotated training samples. In this paper, we present a network and training strategy that relies on the strong use of data augmentation to use the available annotated samples more efficiently. The architecture consists of a contracting path to capture context and a symmetric expanding path that enables precise localization. We show that such a network can be trained end-to-end from very few images and outperforms the prior best method (a sliding-window convolutional network) on the ISBI challenge for segmentation of neuronal structures in electron microscopic stacks. Using the same network trained on transmitted light microscopy images (phase contrast and DIC) we won the ISBI cell tracking challenge 2015 in these categories by a large margin. Moreover, the network is fast. Segmentation of a 512x512 image takes less than a second on a recent GPU. The full implementation (based on Caffe) and the trained networks are available at http://lmb.informatik.uni-freiburg.de/people/ronneber/u-net.* + +## UNet1DModel +[[autodoc]] UNet1DModel + +## UNet1DOutput +[[autodoc]] models.unets.unet_1d.UNet1DOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet2d-cond.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet2d-cond.md new file mode 100644 index 0000000000000000000000000000000000000000..a3cc5da674c353347618ca127e999f4c03bcf7f0 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet2d-cond.md @@ -0,0 +1,31 @@ + + +# UNet2DConditionModel + +The [UNet](https://huggingface.co/papers/1505.04597) model was originally introduced by Ronneberger et al. for biomedical image segmentation, but it is also commonly used in 🤗 Diffusers because it outputs images that are the same size as the input. It is one of the most important components of a diffusion system because it facilitates the actual diffusion process. There are several variants of the UNet model in 🤗 Diffusers, depending on it's number of dimensions and whether it is a conditional model or not. This is a 2D UNet conditional model. + +The abstract from the paper is: + +*There is large consent that successful training of deep networks requires many thousand annotated training samples. In this paper, we present a network and training strategy that relies on the strong use of data augmentation to use the available annotated samples more efficiently. The architecture consists of a contracting path to capture context and a symmetric expanding path that enables precise localization. We show that such a network can be trained end-to-end from very few images and outperforms the prior best method (a sliding-window convolutional network) on the ISBI challenge for segmentation of neuronal structures in electron microscopic stacks. Using the same network trained on transmitted light microscopy images (phase contrast and DIC) we won the ISBI cell tracking challenge 2015 in these categories by a large margin. Moreover, the network is fast. Segmentation of a 512x512 image takes less than a second on a recent GPU. The full implementation (based on Caffe) and the trained networks are available at http://lmb.informatik.uni-freiburg.de/people/ronneber/u-net.* + +## UNet2DConditionModel +[[autodoc]] UNet2DConditionModel + +## UNet2DConditionOutput +[[autodoc]] models.unets.unet_2d_condition.UNet2DConditionOutput + +## FlaxUNet2DConditionModel +[[autodoc]] models.unets.unet_2d_condition_flax.FlaxUNet2DConditionModel + +## FlaxUNet2DConditionOutput +[[autodoc]] models.unets.unet_2d_condition_flax.FlaxUNet2DConditionOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet2d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet2d.md new file mode 100644 index 0000000000000000000000000000000000000000..fe88b8d8ac506308f532f5578d95ea73f912c687 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet2d.md @@ -0,0 +1,25 @@ + + +# UNet2DModel + +The [UNet](https://huggingface.co/papers/1505.04597) model was originally introduced by Ronneberger et al. for biomedical image segmentation, but it is also commonly used in 🤗 Diffusers because it outputs images that are the same size as the input. It is one of the most important components of a diffusion system because it facilitates the actual diffusion process. There are several variants of the UNet model in 🤗 Diffusers, depending on it's number of dimensions and whether it is a conditional model or not. This is a 2D UNet model. + +The abstract from the paper is: + +*There is large consent that successful training of deep networks requires many thousand annotated training samples. In this paper, we present a network and training strategy that relies on the strong use of data augmentation to use the available annotated samples more efficiently. The architecture consists of a contracting path to capture context and a symmetric expanding path that enables precise localization. We show that such a network can be trained end-to-end from very few images and outperforms the prior best method (a sliding-window convolutional network) on the ISBI challenge for segmentation of neuronal structures in electron microscopic stacks. Using the same network trained on transmitted light microscopy images (phase contrast and DIC) we won the ISBI cell tracking challenge 2015 in these categories by a large margin. Moreover, the network is fast. Segmentation of a 512x512 image takes less than a second on a recent GPU. The full implementation (based on Caffe) and the trained networks are available at http://lmb.informatik.uni-freiburg.de/people/ronneber/u-net.* + +## UNet2DModel +[[autodoc]] UNet2DModel + +## UNet2DOutput +[[autodoc]] models.unets.unet_2d.UNet2DOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet3d-cond.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet3d-cond.md new file mode 100644 index 0000000000000000000000000000000000000000..52e3086166ac7d566e37fed5dce521d685cefab8 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/unet3d-cond.md @@ -0,0 +1,25 @@ + + +# UNet3DConditionModel + +The [UNet](https://huggingface.co/papers/1505.04597) model was originally introduced by Ronneberger et al. for biomedical image segmentation, but it is also commonly used in 🤗 Diffusers because it outputs images that are the same size as the input. It is one of the most important components of a diffusion system because it facilitates the actual diffusion process. There are several variants of the UNet model in 🤗 Diffusers, depending on it's number of dimensions and whether it is a conditional model or not. This is a 3D UNet conditional model. + +The abstract from the paper is: + +*There is large consent that successful training of deep networks requires many thousand annotated training samples. In this paper, we present a network and training strategy that relies on the strong use of data augmentation to use the available annotated samples more efficiently. The architecture consists of a contracting path to capture context and a symmetric expanding path that enables precise localization. We show that such a network can be trained end-to-end from very few images and outperforms the prior best method (a sliding-window convolutional network) on the ISBI challenge for segmentation of neuronal structures in electron microscopic stacks. Using the same network trained on transmitted light microscopy images (phase contrast and DIC) we won the ISBI cell tracking challenge 2015 in these categories by a large margin. Moreover, the network is fast. Segmentation of a 512x512 image takes less than a second on a recent GPU. The full implementation (based on Caffe) and the trained networks are available at http://lmb.informatik.uni-freiburg.de/people/ronneber/u-net.* + +## UNet3DConditionModel +[[autodoc]] UNet3DConditionModel + +## UNet3DConditionOutput +[[autodoc]] models.unets.unet_3d_condition.UNet3DConditionOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/uvit2d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/uvit2d.md new file mode 100644 index 0000000000000000000000000000000000000000..abea0fdc38c3aa631ae6b19673b07579e1277569 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/uvit2d.md @@ -0,0 +1,39 @@ + + +# UVit2DModel + +The [U-ViT](https://hf.co/papers/2301.11093) model is a vision transformer (ViT) based UNet. This model incorporates elements from ViT (considers all inputs such as time, conditions and noisy image patches as tokens) and a UNet (long skip connections between the shallow and deep layers). The skip connection is important for predicting pixel-level features. An additional 3x3 convolutional block is applied prior to the final output to improve image quality. + +The abstract from the paper is: + +*Currently, applying diffusion models in pixel space of high resolution images is difficult. Instead, existing approaches focus on diffusion in lower dimensional spaces (latent diffusion), or have multiple super-resolution levels of generation referred to as cascades. The downside is that these approaches add additional complexity to the diffusion framework. This paper aims to improve denoising diffusion for high resolution images while keeping the model as simple as possible. The paper is centered around the research question: How can one train a standard denoising diffusion models on high resolution images, and still obtain performance comparable to these alternate approaches? The four main findings are: 1) the noise schedule should be adjusted for high resolution images, 2) It is sufficient to scale only a particular part of the architecture, 3) dropout should be added at specific locations in the architecture, and 4) downsampling is an effective strategy to avoid high resolution feature maps. Combining these simple yet effective techniques, we achieve state-of-the-art on image generation among diffusion models without sampling modifiers on ImageNet.* + +## UVit2DModel + +[[autodoc]] UVit2DModel + +## UVit2DConvEmbed + +[[autodoc]] models.unets.uvit_2d.UVit2DConvEmbed + +## UVitBlock + +[[autodoc]] models.unets.uvit_2d.UVitBlock + +## ConvNextBlock + +[[autodoc]] models.unets.uvit_2d.ConvNextBlock + +## ConvMlmLayer + +[[autodoc]] models.unets.uvit_2d.ConvMlmLayer diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/vq.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/vq.md new file mode 100644 index 0000000000000000000000000000000000000000..fa0631e6fe0bae581a6d3e33382b9b9d3babac9f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/vq.md @@ -0,0 +1,27 @@ + + +# VQModel + +The VQ-VAE model was introduced in [Neural Discrete Representation Learning](https://huggingface.co/papers/1711.00937) by Aaron van den Oord, Oriol Vinyals and Koray Kavukcuoglu. The model is used in 🤗 Diffusers to decode latent representations into images. Unlike [`AutoencoderKL`], the [`VQModel`] works in a quantized latent space. + +The abstract from the paper is: + +*Learning useful representations without supervision remains a key challenge in machine learning. In this paper, we propose a simple yet powerful generative model that learns such discrete representations. Our model, the Vector Quantised-Variational AutoEncoder (VQ-VAE), differs from VAEs in two key ways: the encoder network outputs discrete, rather than continuous, codes; and the prior is learnt rather than static. In order to learn a discrete latent representation, we incorporate ideas from vector quantisation (VQ). Using the VQ method allows the model to circumvent issues of "posterior collapse" -- where the latents are ignored when they are paired with a powerful autoregressive decoder -- typically observed in the VAE framework. Pairing these representations with an autoregressive prior, the model can generate high quality images, videos, and speech as well as doing high quality speaker conversion and unsupervised learning of phonemes, providing further evidence of the utility of the learnt representations.* + +## VQModel + +[[autodoc]] VQModel + +## VQEncoderOutput + +[[autodoc]] models.autoencoders.vq_model.VQEncoderOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/wan_transformer_3d.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/wan_transformer_3d.md new file mode 100644 index 0000000000000000000000000000000000000000..56015c4c07f172b9ea619eb300655d68f638c22a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/models/wan_transformer_3d.md @@ -0,0 +1,30 @@ + + +# WanTransformer3DModel + +A Diffusion Transformer model for 3D video-like data was introduced in [Wan 2.1](https://github.com/Wan-Video/Wan2.1) by the Alibaba Wan Team. + +The model can be loaded with the following code snippet. + +```python +from diffusers import WanTransformer3DModel + +transformer = WanTransformer3DModel.from_pretrained("Wan-AI/Wan2.1-T2V-1.3B-Diffusers", subfolder="transformer", torch_dtype=torch.bfloat16) +``` + +## WanTransformer3DModel + +[[autodoc]] WanTransformer3DModel + +## Transformer2DModelOutput + +[[autodoc]] models.modeling_outputs.Transformer2DModelOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/normalization.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/normalization.md new file mode 100644 index 0000000000000000000000000000000000000000..05ae92a28dc8261e2c4f15fc21872a09e837ef1e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/normalization.md @@ -0,0 +1,71 @@ + + +# Normalization layers + +Customized normalization layers for supporting various models in 🤗 Diffusers. + +## AdaLayerNorm + +[[autodoc]] models.normalization.AdaLayerNorm + +## AdaLayerNormZero + +[[autodoc]] models.normalization.AdaLayerNormZero + +## AdaLayerNormSingle + +[[autodoc]] models.normalization.AdaLayerNormSingle + +## AdaGroupNorm + +[[autodoc]] models.normalization.AdaGroupNorm + +## AdaLayerNormContinuous + +[[autodoc]] models.normalization.AdaLayerNormContinuous + +## RMSNorm + +[[autodoc]] models.normalization.RMSNorm + +## GlobalResponseNorm + +[[autodoc]] models.normalization.GlobalResponseNorm + + +## LuminaLayerNormContinuous +[[autodoc]] models.normalization.LuminaLayerNormContinuous + +## SD35AdaLayerNormZeroX +[[autodoc]] models.normalization.SD35AdaLayerNormZeroX + +## AdaLayerNormZeroSingle +[[autodoc]] models.normalization.AdaLayerNormZeroSingle + +## LuminaRMSNormZero +[[autodoc]] models.normalization.LuminaRMSNormZero + +## LpNorm +[[autodoc]] models.normalization.LpNorm + +## CogView3PlusAdaLayerNormZeroTextImage +[[autodoc]] models.normalization.CogView3PlusAdaLayerNormZeroTextImage + +## CogVideoXLayerNormZero +[[autodoc]] models.normalization.CogVideoXLayerNormZero + +## MochiRMSNormZero +[[autodoc]] models.transformers.transformer_mochi.MochiRMSNormZero + +## MochiRMSNorm +[[autodoc]] models.normalization.MochiRMSNorm \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/outputs.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/outputs.md new file mode 100644 index 0000000000000000000000000000000000000000..759444852ba08c0da64bbb3c294458bec176e991 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/outputs.md @@ -0,0 +1,67 @@ + + +# Outputs + +All model outputs are subclasses of [`~utils.BaseOutput`], data structures containing all the information returned by the model. The outputs can also be used as tuples or dictionaries. + +For example: + +```python +from diffusers import DDIMPipeline + +pipeline = DDIMPipeline.from_pretrained("google/ddpm-cifar10-32") +outputs = pipeline() +``` + +The `outputs` object is a [`~pipelines.ImagePipelineOutput`] which means it has an image attribute. + +You can access each attribute as you normally would or with a keyword lookup, and if that attribute is not returned by the model, you will get `None`: + +```python +outputs.images +outputs["images"] +``` + +When considering the `outputs` object as a tuple, it only considers the attributes that don't have `None` values. +For instance, retrieving an image by indexing into it returns the tuple `(outputs.images)`: + +```python +outputs[:1] +``` + + + +To check a specific pipeline or model output, refer to its corresponding API documentation. + + + +## BaseOutput + +[[autodoc]] utils.BaseOutput + - to_tuple + +## ImagePipelineOutput + +[[autodoc]] pipelines.ImagePipelineOutput + +## FlaxImagePipelineOutput + +[[autodoc]] pipelines.pipeline_flax_utils.FlaxImagePipelineOutput + +## AudioPipelineOutput + +[[autodoc]] pipelines.AudioPipelineOutput + +## ImageTextPipelineOutput + +[[autodoc]] ImageTextPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/allegro.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/allegro.md new file mode 100644 index 0000000000000000000000000000000000000000..690f8096a0e4d64e1557c57a3426f880be5af1e2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/allegro.md @@ -0,0 +1,79 @@ + + +# Allegro + +[Allegro: Open the Black Box of Commercial-Level Video Generation Model](https://huggingface.co/papers/2410.15458) from RhymesAI, by Yuan Zhou, Qiuyue Wang, Yuxuan Cai, Huan Yang. + +The abstract from the paper is: + +*Significant advancements have been made in the field of video generation, with the open-source community contributing a wealth of research papers and tools for training high-quality models. However, despite these efforts, the available information and resources remain insufficient for achieving commercial-level performance. In this report, we open the black box and introduce Allegro, an advanced video generation model that excels in both quality and temporal consistency. We also highlight the current limitations in the field and present a comprehensive methodology for training high-performance, commercial-level video generation models, addressing key aspects such as data, model architecture, training pipeline, and evaluation. Our user study shows that Allegro surpasses existing open-source models and most commercial models, ranking just behind Hailuo and Kling. Code: https://github.com/rhymes-ai/Allegro , Model: https://huggingface.co/rhymes-ai/Allegro , Gallery: https://rhymes.ai/allegro_gallery .* + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`AllegroPipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, AllegroTransformer3DModel, AllegroPipeline +from diffusers.utils import export_to_video +from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel + +quant_config = BitsAndBytesConfig(load_in_8bit=True) +text_encoder_8bit = T5EncoderModel.from_pretrained( + "rhymes-ai/Allegro", + subfolder="text_encoder", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = AllegroTransformer3DModel.from_pretrained( + "rhymes-ai/Allegro", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +pipeline = AllegroPipeline.from_pretrained( + "rhymes-ai/Allegro", + text_encoder=text_encoder_8bit, + transformer=transformer_8bit, + torch_dtype=torch.float16, + device_map="balanced", +) + +prompt = ( + "A seaside harbor with bright sunlight and sparkling seawater, with many boats in the water. From an aerial view, " + "the boats vary in size and color, some moving and some stationary. Fishing boats in the water suggest that this " + "location might be a popular spot for docking fishing boats." +) +video = pipeline(prompt, guidance_scale=7.5, max_sequence_length=512).frames[0] +export_to_video(video, "harbor.mp4", fps=15) +``` + +## AllegroPipeline + +[[autodoc]] AllegroPipeline + - all + - __call__ + +## AllegroPipelineOutput + +[[autodoc]] pipelines.allegro.pipeline_output.AllegroPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/amused.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/amused.md new file mode 100644 index 0000000000000000000000000000000000000000..6fbd7286a62db9929d146ad72e7b8a3a6e977f69 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/amused.md @@ -0,0 +1,48 @@ + + +# aMUSEd + +aMUSEd was introduced in [aMUSEd: An Open MUSE Reproduction](https://huggingface.co/papers/2401.01808) by Suraj Patil, William Berman, Robin Rombach, and Patrick von Platen. + +Amused is a lightweight text to image model based off of the [MUSE](https://huggingface.co/papers/2301.00704) architecture. Amused is particularly useful in applications that require a lightweight and fast model such as generating many images quickly at once. + +Amused is a vqvae token based transformer that can generate an image in fewer forward passes than many diffusion models. In contrast with muse, it uses the smaller text encoder CLIP-L/14 instead of t5-xxl. Due to its small parameter count and few forward pass generation process, amused can generate many images quickly. This benefit is seen particularly at larger batch sizes. + +The abstract from the paper is: + +*We present aMUSEd, an open-source, lightweight masked image model (MIM) for text-to-image generation based on MUSE. With 10 percent of MUSE's parameters, aMUSEd is focused on fast image generation. We believe MIM is under-explored compared to latent diffusion, the prevailing approach for text-to-image generation. Compared to latent diffusion, MIM requires fewer inference steps and is more interpretable. Additionally, MIM can be fine-tuned to learn additional styles with only a single image. We hope to encourage further exploration of MIM by demonstrating its effectiveness on large-scale text-to-image generation and releasing reproducible training code. We also release checkpoints for two models which directly produce images at 256x256 and 512x512 resolutions.* + +| Model | Params | +|-------|--------| +| [amused-256](https://huggingface.co/amused/amused-256) | 603M | +| [amused-512](https://huggingface.co/amused/amused-512) | 608M | + +## AmusedPipeline + +[[autodoc]] AmusedPipeline + - __call__ + - all + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + +[[autodoc]] AmusedImg2ImgPipeline + - __call__ + - all + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + +[[autodoc]] AmusedInpaintPipeline + - __call__ + - all + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/animatediff.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/animatediff.md new file mode 100644 index 0000000000000000000000000000000000000000..e4a34c12e16da0be84fac5369350dd445d127d8d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/animatediff.md @@ -0,0 +1,1056 @@ + + +# Text-to-Video Generation with AnimateDiff + +
+ LoRA +
+ +## Overview + +[AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning](https://huggingface.co/papers/2307.04725) by Yuwei Guo, Ceyuan Yang, Anyi Rao, Yaohui Wang, Yu Qiao, Dahua Lin, Bo Dai. + +The abstract of the paper is the following: + +*With the advance of text-to-image models (e.g., Stable Diffusion) and corresponding personalization techniques such as DreamBooth and LoRA, everyone can manifest their imagination into high-quality images at an affordable cost. Subsequently, there is a great demand for image animation techniques to further combine generated static images with motion dynamics. In this report, we propose a practical framework to animate most of the existing personalized text-to-image models once and for all, saving efforts in model-specific tuning. At the core of the proposed framework is to insert a newly initialized motion modeling module into the frozen text-to-image model and train it on video clips to distill reasonable motion priors. Once trained, by simply injecting this motion modeling module, all personalized versions derived from the same base T2I readily become text-driven models that produce diverse and personalized animated images. We conduct our evaluation on several public representative personalized text-to-image models across anime pictures and realistic photographs, and demonstrate that our proposed framework helps these models generate temporally smooth animation clips while preserving the domain and diversity of their outputs. Code and pre-trained weights will be publicly available at [this https URL](https://animatediff.github.io/).* + +## Available Pipelines + +| Pipeline | Tasks | Demo +|---|---|:---:| +| [AnimateDiffPipeline](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/animatediff/pipeline_animatediff.py) | *Text-to-Video Generation with AnimateDiff* | +| [AnimateDiffControlNetPipeline](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/animatediff/pipeline_animatediff_controlnet.py) | *Controlled Video-to-Video Generation with AnimateDiff using ControlNet* | +| [AnimateDiffSparseControlNetPipeline](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/animatediff/pipeline_animatediff_sparsectrl.py) | *Controlled Video-to-Video Generation with AnimateDiff using SparseCtrl* | +| [AnimateDiffSDXLPipeline](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/animatediff/pipeline_animatediff_sdxl.py) | *Video-to-Video Generation with AnimateDiff* | +| [AnimateDiffVideoToVideoPipeline](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/animatediff/pipeline_animatediff_video2video.py) | *Video-to-Video Generation with AnimateDiff* | +| [AnimateDiffVideoToVideoControlNetPipeline](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/animatediff/pipeline_animatediff_video2video_controlnet.py) | *Video-to-Video Generation with AnimateDiff using ControlNet* | + +## Available checkpoints + +Motion Adapter checkpoints can be found under [guoyww](https://huggingface.co/guoyww/). These checkpoints are meant to work with any model based on Stable Diffusion 1.4/1.5. + +## Usage example + +### AnimateDiffPipeline + +AnimateDiff works with a MotionAdapter checkpoint and a Stable Diffusion model checkpoint. The MotionAdapter is a collection of Motion Modules that are responsible for adding coherent motion across image frames. These modules are applied after the Resnet and Attention blocks in Stable Diffusion UNet. + +The following example demonstrates how to use a *MotionAdapter* checkpoint with Diffusers for inference based on StableDiffusion-1.4/1.5. + +```python +import torch +from diffusers import AnimateDiffPipeline, DDIMScheduler, MotionAdapter +from diffusers.utils import export_to_gif + +# Load the motion adapter +adapter = MotionAdapter.from_pretrained("guoyww/animatediff-motion-adapter-v1-5-2", torch_dtype=torch.float16) +# load SD 1.5 based finetuned model +model_id = "SG161222/Realistic_Vision_V5.1_noVAE" +pipe = AnimateDiffPipeline.from_pretrained(model_id, motion_adapter=adapter, torch_dtype=torch.float16) +scheduler = DDIMScheduler.from_pretrained( + model_id, + subfolder="scheduler", + clip_sample=False, + timestep_spacing="linspace", + beta_schedule="linear", + steps_offset=1, +) +pipe.scheduler = scheduler + +# enable memory savings +pipe.enable_vae_slicing() +pipe.enable_model_cpu_offload() + +output = pipe( + prompt=( + "masterpiece, bestquality, highlydetailed, ultradetailed, sunset, " + "orange sky, warm lighting, fishing boats, ocean waves seagulls, " + "rippling water, wharf, silhouette, serene atmosphere, dusk, evening glow, " + "golden hour, coastal landscape, seaside scenery" + ), + negative_prompt="bad quality, worse quality", + num_frames=16, + guidance_scale=7.5, + num_inference_steps=25, + generator=torch.Generator("cpu").manual_seed(42), +) +frames = output.frames[0] +export_to_gif(frames, "animation.gif") +``` + +Here are some sample outputs: + + + + + +
+ masterpiece, bestquality, sunset. +
+ masterpiece, bestquality, sunset +
+ + + +AnimateDiff tends to work better with finetuned Stable Diffusion models. If you plan on using a scheduler that can clip samples, make sure to disable it by setting `clip_sample=False` in the scheduler as this can also have an adverse effect on generated samples. Additionally, the AnimateDiff checkpoints can be sensitive to the beta schedule of the scheduler. We recommend setting this to `linear`. + + + +### AnimateDiffControlNetPipeline + +AnimateDiff can also be used with ControlNets ControlNet was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, and Maneesh Agrawala. With a ControlNet model, you can provide an additional control image to condition and control Stable Diffusion generation. For example, if you provide depth maps, the ControlNet model generates a video that'll preserve the spatial information from the depth maps. It is a more flexible and accurate way to control the video generation process. + +```python +import torch +from diffusers import AnimateDiffControlNetPipeline, AutoencoderKL, ControlNetModel, MotionAdapter, LCMScheduler +from diffusers.utils import export_to_gif, load_video + +# Additionally, you will need a preprocess videos before they can be used with the ControlNet +# HF maintains just the right package for it: `pip install controlnet_aux` +from controlnet_aux.processor import ZoeDetector + +# Download controlnets from https://huggingface.co/lllyasviel/ControlNet-v1-1 to use .from_single_file +# Download Diffusers-format controlnets, such as https://huggingface.co/lllyasviel/sd-controlnet-depth, to use .from_pretrained() +controlnet = ControlNetModel.from_single_file("control_v11f1p_sd15_depth.pth", torch_dtype=torch.float16) + +# We use AnimateLCM for this example but one can use the original motion adapters as well (for example, https://huggingface.co/guoyww/animatediff-motion-adapter-v1-5-3) +motion_adapter = MotionAdapter.from_pretrained("wangfuyun/AnimateLCM") + +vae = AutoencoderKL.from_pretrained("stabilityai/sd-vae-ft-mse", torch_dtype=torch.float16) +pipe: AnimateDiffControlNetPipeline = AnimateDiffControlNetPipeline.from_pretrained( + "SG161222/Realistic_Vision_V5.1_noVAE", + motion_adapter=motion_adapter, + controlnet=controlnet, + vae=vae, +).to(device="cuda", dtype=torch.float16) +pipe.scheduler = LCMScheduler.from_config(pipe.scheduler.config, beta_schedule="linear") +pipe.load_lora_weights("wangfuyun/AnimateLCM", weight_name="AnimateLCM_sd15_t2v_lora.safetensors", adapter_name="lcm-lora") +pipe.set_adapters(["lcm-lora"], [0.8]) + +depth_detector = ZoeDetector.from_pretrained("lllyasviel/Annotators").to("cuda") +video = load_video("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/animatediff-vid2vid-input-1.gif") +conditioning_frames = [] + +with pipe.progress_bar(total=len(video)) as progress_bar: + for frame in video: + conditioning_frames.append(depth_detector(frame)) + progress_bar.update() + +prompt = "a panda, playing a guitar, sitting in a pink boat, in the ocean, mountains in background, realistic, high quality" +negative_prompt = "bad quality, worst quality" + +video = pipe( + prompt=prompt, + negative_prompt=negative_prompt, + num_frames=len(video), + num_inference_steps=10, + guidance_scale=2.0, + conditioning_frames=conditioning_frames, + generator=torch.Generator().manual_seed(42), +).frames[0] + +export_to_gif(video, "animatediff_controlnet.gif", fps=8) +``` + +Here are some sample outputs: + + + + + + + + + + +
Source VideoOutput Video
+ raccoon playing a guitar +
+ racoon playing a guitar +
+ a panda, playing a guitar, sitting in a pink boat, in the ocean, mountains in background, realistic, high quality +
+ +### AnimateDiffSparseControlNetPipeline + +[SparseCtrl: Adding Sparse Controls to Text-to-Video Diffusion Models](https://huggingface.co/papers/2311.16933) for achieving controlled generation in text-to-video diffusion models by Yuwei Guo, Ceyuan Yang, Anyi Rao, Maneesh Agrawala, Dahua Lin, and Bo Dai. + +The abstract from the paper is: + +*The development of text-to-video (T2V), i.e., generating videos with a given text prompt, has been significantly advanced in recent years. However, relying solely on text prompts often results in ambiguous frame composition due to spatial uncertainty. The research community thus leverages the dense structure signals, e.g., per-frame depth/edge sequences, to enhance controllability, whose collection accordingly increases the burden of inference. In this work, we present SparseCtrl to enable flexible structure control with temporally sparse signals, requiring only one or a few inputs, as shown in Figure 1. It incorporates an additional condition encoder to process these sparse signals while leaving the pre-trained T2V model untouched. The proposed approach is compatible with various modalities, including sketches, depth maps, and RGB images, providing more practical control for video generation and promoting applications such as storyboarding, depth rendering, keyframe animation, and interpolation. Extensive experiments demonstrate the generalization of SparseCtrl on both original and personalized T2V generators. Codes and models will be publicly available at [this https URL](https://guoyww.github.io/projects/SparseCtrl).* + +SparseCtrl introduces the following checkpoints for controlled text-to-video generation: + +- [SparseCtrl Scribble](https://huggingface.co/guoyww/animatediff-sparsectrl-scribble) +- [SparseCtrl RGB](https://huggingface.co/guoyww/animatediff-sparsectrl-rgb) + +#### Using SparseCtrl Scribble + +```python +import torch + +from diffusers import AnimateDiffSparseControlNetPipeline +from diffusers.models import AutoencoderKL, MotionAdapter, SparseControlNetModel +from diffusers.schedulers import DPMSolverMultistepScheduler +from diffusers.utils import export_to_gif, load_image + + +model_id = "SG161222/Realistic_Vision_V5.1_noVAE" +motion_adapter_id = "guoyww/animatediff-motion-adapter-v1-5-3" +controlnet_id = "guoyww/animatediff-sparsectrl-scribble" +lora_adapter_id = "guoyww/animatediff-motion-lora-v1-5-3" +vae_id = "stabilityai/sd-vae-ft-mse" +device = "cuda" + +motion_adapter = MotionAdapter.from_pretrained(motion_adapter_id, torch_dtype=torch.float16).to(device) +controlnet = SparseControlNetModel.from_pretrained(controlnet_id, torch_dtype=torch.float16).to(device) +vae = AutoencoderKL.from_pretrained(vae_id, torch_dtype=torch.float16).to(device) +scheduler = DPMSolverMultistepScheduler.from_pretrained( + model_id, + subfolder="scheduler", + beta_schedule="linear", + algorithm_type="dpmsolver++", + use_karras_sigmas=True, +) +pipe = AnimateDiffSparseControlNetPipeline.from_pretrained( + model_id, + motion_adapter=motion_adapter, + controlnet=controlnet, + vae=vae, + scheduler=scheduler, + torch_dtype=torch.float16, +).to(device) +pipe.load_lora_weights(lora_adapter_id, adapter_name="motion_lora") +pipe.fuse_lora(lora_scale=1.0) + +prompt = "an aerial view of a cyberpunk city, night time, neon lights, masterpiece, high quality" +negative_prompt = "low quality, worst quality, letterboxed" + +image_files = [ + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/animatediff-scribble-1.png", + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/animatediff-scribble-2.png", + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/animatediff-scribble-3.png" +] +condition_frame_indices = [0, 8, 15] +conditioning_frames = [load_image(img_file) for img_file in image_files] + +video = pipe( + prompt=prompt, + negative_prompt=negative_prompt, + num_inference_steps=25, + conditioning_frames=conditioning_frames, + controlnet_conditioning_scale=1.0, + controlnet_frame_indices=condition_frame_indices, + generator=torch.Generator().manual_seed(1337), +).frames[0] +export_to_gif(video, "output.gif") +``` + +Here are some sample outputs: + + + +
+ an aerial view of a cyberpunk city, night time, neon lights, masterpiece, high quality +
+ + + + + + + + + +
+
+ scribble-1 +
+
+
+ scribble-2 +
+
+
+ scribble-3 +
+
+
+ an aerial view of a cyberpunk city, night time, neon lights, masterpiece, high quality +
+
+ +#### Using SparseCtrl RGB + +```python +import torch + +from diffusers import AnimateDiffSparseControlNetPipeline +from diffusers.models import AutoencoderKL, MotionAdapter, SparseControlNetModel +from diffusers.schedulers import DPMSolverMultistepScheduler +from diffusers.utils import export_to_gif, load_image + + +model_id = "SG161222/Realistic_Vision_V5.1_noVAE" +motion_adapter_id = "guoyww/animatediff-motion-adapter-v1-5-3" +controlnet_id = "guoyww/animatediff-sparsectrl-rgb" +lora_adapter_id = "guoyww/animatediff-motion-lora-v1-5-3" +vae_id = "stabilityai/sd-vae-ft-mse" +device = "cuda" + +motion_adapter = MotionAdapter.from_pretrained(motion_adapter_id, torch_dtype=torch.float16).to(device) +controlnet = SparseControlNetModel.from_pretrained(controlnet_id, torch_dtype=torch.float16).to(device) +vae = AutoencoderKL.from_pretrained(vae_id, torch_dtype=torch.float16).to(device) +scheduler = DPMSolverMultistepScheduler.from_pretrained( + model_id, + subfolder="scheduler", + beta_schedule="linear", + algorithm_type="dpmsolver++", + use_karras_sigmas=True, +) +pipe = AnimateDiffSparseControlNetPipeline.from_pretrained( + model_id, + motion_adapter=motion_adapter, + controlnet=controlnet, + vae=vae, + scheduler=scheduler, + torch_dtype=torch.float16, +).to(device) +pipe.load_lora_weights(lora_adapter_id, adapter_name="motion_lora") + +image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/animatediff-firework.png") + +video = pipe( + prompt="closeup face photo of man in black clothes, night city street, bokeh, fireworks in background", + negative_prompt="low quality, worst quality", + num_inference_steps=25, + conditioning_frames=image, + controlnet_frame_indices=[0], + controlnet_conditioning_scale=1.0, + generator=torch.Generator().manual_seed(42), +).frames[0] +export_to_gif(video, "output.gif") +``` + +Here are some sample outputs: + + + +
+ closeup face photo of man in black clothes, night city street, bokeh, fireworks in background +
+ + + + + +
+
+ closeup face photo of man in black clothes, night city street, bokeh, fireworks in background +
+
+
+ closeup face photo of man in black clothes, night city street, bokeh, fireworks in background +
+
+ +### AnimateDiffSDXLPipeline + +AnimateDiff can also be used with SDXL models. This is currently an experimental feature as only a beta release of the motion adapter checkpoint is available. + +```python +import torch +from diffusers.models import MotionAdapter +from diffusers import AnimateDiffSDXLPipeline, DDIMScheduler +from diffusers.utils import export_to_gif + +adapter = MotionAdapter.from_pretrained("guoyww/animatediff-motion-adapter-sdxl-beta", torch_dtype=torch.float16) + +model_id = "stabilityai/stable-diffusion-xl-base-1.0" +scheduler = DDIMScheduler.from_pretrained( + model_id, + subfolder="scheduler", + clip_sample=False, + timestep_spacing="linspace", + beta_schedule="linear", + steps_offset=1, +) +pipe = AnimateDiffSDXLPipeline.from_pretrained( + model_id, + motion_adapter=adapter, + scheduler=scheduler, + torch_dtype=torch.float16, + variant="fp16", +).to("cuda") + +# enable memory savings +pipe.enable_vae_slicing() +pipe.enable_vae_tiling() + +output = pipe( + prompt="a panda surfing in the ocean, realistic, high quality", + negative_prompt="low quality, worst quality", + num_inference_steps=20, + guidance_scale=8, + width=1024, + height=1024, + num_frames=16, +) + +frames = output.frames[0] +export_to_gif(frames, "animation.gif") +``` + +### AnimateDiffVideoToVideoPipeline + +AnimateDiff can also be used to generate visually similar videos or enable style/character/background or other edits starting from an initial video, allowing you to seamlessly explore creative possibilities. + +```python +import imageio +import requests +import torch +from diffusers import AnimateDiffVideoToVideoPipeline, DDIMScheduler, MotionAdapter +from diffusers.utils import export_to_gif +from io import BytesIO +from PIL import Image + +# Load the motion adapter +adapter = MotionAdapter.from_pretrained("guoyww/animatediff-motion-adapter-v1-5-2", torch_dtype=torch.float16) +# load SD 1.5 based finetuned model +model_id = "SG161222/Realistic_Vision_V5.1_noVAE" +pipe = AnimateDiffVideoToVideoPipeline.from_pretrained(model_id, motion_adapter=adapter, torch_dtype=torch.float16) +scheduler = DDIMScheduler.from_pretrained( + model_id, + subfolder="scheduler", + clip_sample=False, + timestep_spacing="linspace", + beta_schedule="linear", + steps_offset=1, +) +pipe.scheduler = scheduler + +# enable memory savings +pipe.enable_vae_slicing() +pipe.enable_model_cpu_offload() + +# helper function to load videos +def load_video(file_path: str): + images = [] + + if file_path.startswith(('http://', 'https://')): + # If the file_path is a URL + response = requests.get(file_path) + response.raise_for_status() + content = BytesIO(response.content) + vid = imageio.get_reader(content) + else: + # Assuming it's a local file path + vid = imageio.get_reader(file_path) + + for frame in vid: + pil_image = Image.fromarray(frame) + images.append(pil_image) + + return images + +video = load_video("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/animatediff-vid2vid-input-1.gif") + +output = pipe( + video = video, + prompt="panda playing a guitar, on a boat, in the ocean, high quality", + negative_prompt="bad quality, worse quality", + guidance_scale=7.5, + num_inference_steps=25, + strength=0.5, + generator=torch.Generator("cpu").manual_seed(42), +) +frames = output.frames[0] +export_to_gif(frames, "animation.gif") +``` + +Here are some sample outputs: + + + + + + + + + + + + + + +
Source VideoOutput Video
+ raccoon playing a guitar +
+ racoon playing a guitar +
+ panda playing a guitar +
+ closeup of margot robbie, fireworks in the background, high quality +
+ closeup of tony stark, robert downey jr, fireworks +
+ + + +### AnimateDiffVideoToVideoControlNetPipeline + +AnimateDiff can be used together with ControlNets to enhance video-to-video generation by allowing for precise control over the output. ControlNet was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, and Maneesh Agrawala, and allows you to condition Stable Diffusion with an additional control image to ensure that the spatial information is preserved throughout the video. + +This pipeline allows you to condition your generation both on the original video and on a sequence of control images. + +```python +import torch +from PIL import Image +from tqdm.auto import tqdm + +from controlnet_aux.processor import OpenposeDetector +from diffusers import AnimateDiffVideoToVideoControlNetPipeline +from diffusers.utils import export_to_gif, load_video +from diffusers import AutoencoderKL, ControlNetModel, MotionAdapter, LCMScheduler + +# Load the ControlNet +controlnet = ControlNetModel.from_pretrained("lllyasviel/sd-controlnet-openpose", torch_dtype=torch.float16) +# Load the motion adapter +motion_adapter = MotionAdapter.from_pretrained("wangfuyun/AnimateLCM") +# Load SD 1.5 based finetuned model +vae = AutoencoderKL.from_pretrained("stabilityai/sd-vae-ft-mse", torch_dtype=torch.float16) +pipe = AnimateDiffVideoToVideoControlNetPipeline.from_pretrained( + "SG161222/Realistic_Vision_V5.1_noVAE", + motion_adapter=motion_adapter, + controlnet=controlnet, + vae=vae, +).to(device="cuda", dtype=torch.float16) + +# Enable LCM to speed up inference +pipe.scheduler = LCMScheduler.from_config(pipe.scheduler.config, beta_schedule="linear") +pipe.load_lora_weights("wangfuyun/AnimateLCM", weight_name="AnimateLCM_sd15_t2v_lora.safetensors", adapter_name="lcm-lora") +pipe.set_adapters(["lcm-lora"], [0.8]) + +video = load_video("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/dance.gif") +video = [frame.convert("RGB") for frame in video] + +prompt = "astronaut in space, dancing" +negative_prompt = "bad quality, worst quality, jpeg artifacts, ugly" + +# Create controlnet preprocessor +open_pose = OpenposeDetector.from_pretrained("lllyasviel/Annotators").to("cuda") + +# Preprocess controlnet images +conditioning_frames = [] +for frame in tqdm(video): + conditioning_frames.append(open_pose(frame)) + +strength = 0.8 +with torch.inference_mode(): + video = pipe( + video=video, + prompt=prompt, + negative_prompt=negative_prompt, + num_inference_steps=10, + guidance_scale=2.0, + controlnet_conditioning_scale=0.75, + conditioning_frames=conditioning_frames, + strength=strength, + generator=torch.Generator().manual_seed(42), + ).frames[0] + +video = [frame.resize(conditioning_frames[0].size) for frame in video] +export_to_gif(video, f"animatediff_vid2vid_controlnet.gif", fps=8) +``` + +Here are some sample outputs: + + + + + + + + + + +
Source VideoOutput Video
+ anime girl, dancing +
+ astronaut in space, dancing +
+ +**The lights and composition were transferred from the Source Video.** + +## Using Motion LoRAs + +Motion LoRAs are a collection of LoRAs that work with the `guoyww/animatediff-motion-adapter-v1-5-2` checkpoint. These LoRAs are responsible for adding specific types of motion to the animations. + +```python +import torch +from diffusers import AnimateDiffPipeline, DDIMScheduler, MotionAdapter +from diffusers.utils import export_to_gif + +# Load the motion adapter +adapter = MotionAdapter.from_pretrained("guoyww/animatediff-motion-adapter-v1-5-2", torch_dtype=torch.float16) +# load SD 1.5 based finetuned model +model_id = "SG161222/Realistic_Vision_V5.1_noVAE" +pipe = AnimateDiffPipeline.from_pretrained(model_id, motion_adapter=adapter, torch_dtype=torch.float16) +pipe.load_lora_weights( + "guoyww/animatediff-motion-lora-zoom-out", adapter_name="zoom-out" +) + +scheduler = DDIMScheduler.from_pretrained( + model_id, + subfolder="scheduler", + clip_sample=False, + beta_schedule="linear", + timestep_spacing="linspace", + steps_offset=1, +) +pipe.scheduler = scheduler + +# enable memory savings +pipe.enable_vae_slicing() +pipe.enable_model_cpu_offload() + +output = pipe( + prompt=( + "masterpiece, bestquality, highlydetailed, ultradetailed, sunset, " + "orange sky, warm lighting, fishing boats, ocean waves seagulls, " + "rippling water, wharf, silhouette, serene atmosphere, dusk, evening glow, " + "golden hour, coastal landscape, seaside scenery" + ), + negative_prompt="bad quality, worse quality", + num_frames=16, + guidance_scale=7.5, + num_inference_steps=25, + generator=torch.Generator("cpu").manual_seed(42), +) +frames = output.frames[0] +export_to_gif(frames, "animation.gif") +``` + + + + + +
+ masterpiece, bestquality, sunset. +
+ masterpiece, bestquality, sunset +
+ +## Using Motion LoRAs with PEFT + +You can also leverage the [PEFT](https://github.com/huggingface/peft) backend to combine Motion LoRA's and create more complex animations. + +First install PEFT with + +```shell +pip install peft +``` + +Then you can use the following code to combine Motion LoRAs. + +```python +import torch +from diffusers import AnimateDiffPipeline, DDIMScheduler, MotionAdapter +from diffusers.utils import export_to_gif + +# Load the motion adapter +adapter = MotionAdapter.from_pretrained("guoyww/animatediff-motion-adapter-v1-5-2", torch_dtype=torch.float16) +# load SD 1.5 based finetuned model +model_id = "SG161222/Realistic_Vision_V5.1_noVAE" +pipe = AnimateDiffPipeline.from_pretrained(model_id, motion_adapter=adapter, torch_dtype=torch.float16) + +pipe.load_lora_weights( + "diffusers/animatediff-motion-lora-zoom-out", adapter_name="zoom-out", +) +pipe.load_lora_weights( + "diffusers/animatediff-motion-lora-pan-left", adapter_name="pan-left", +) +pipe.set_adapters(["zoom-out", "pan-left"], adapter_weights=[1.0, 1.0]) + +scheduler = DDIMScheduler.from_pretrained( + model_id, + subfolder="scheduler", + clip_sample=False, + timestep_spacing="linspace", + beta_schedule="linear", + steps_offset=1, +) +pipe.scheduler = scheduler + +# enable memory savings +pipe.enable_vae_slicing() +pipe.enable_model_cpu_offload() + +output = pipe( + prompt=( + "masterpiece, bestquality, highlydetailed, ultradetailed, sunset, " + "orange sky, warm lighting, fishing boats, ocean waves seagulls, " + "rippling water, wharf, silhouette, serene atmosphere, dusk, evening glow, " + "golden hour, coastal landscape, seaside scenery" + ), + negative_prompt="bad quality, worse quality", + num_frames=16, + guidance_scale=7.5, + num_inference_steps=25, + generator=torch.Generator("cpu").manual_seed(42), +) +frames = output.frames[0] +export_to_gif(frames, "animation.gif") +``` + + + + + +
+ masterpiece, bestquality, sunset. +
+ masterpiece, bestquality, sunset +
+ +## Using FreeInit + +[FreeInit: Bridging Initialization Gap in Video Diffusion Models](https://huggingface.co/papers/2312.07537) by Tianxing Wu, Chenyang Si, Yuming Jiang, Ziqi Huang, Ziwei Liu. + +FreeInit is an effective method that improves temporal consistency and overall quality of videos generated using video-diffusion-models without any addition training. It can be applied to AnimateDiff, ModelScope, VideoCrafter and various other video generation models seamlessly at inference time, and works by iteratively refining the latent-initialization noise. More details can be found it the paper. + +The following example demonstrates the usage of FreeInit. + +```python +import torch +from diffusers import MotionAdapter, AnimateDiffPipeline, DDIMScheduler +from diffusers.utils import export_to_gif + +adapter = MotionAdapter.from_pretrained("guoyww/animatediff-motion-adapter-v1-5-2") +model_id = "SG161222/Realistic_Vision_V5.1_noVAE" +pipe = AnimateDiffPipeline.from_pretrained(model_id, motion_adapter=adapter, torch_dtype=torch.float16).to("cuda") +pipe.scheduler = DDIMScheduler.from_pretrained( + model_id, + subfolder="scheduler", + beta_schedule="linear", + clip_sample=False, + timestep_spacing="linspace", + steps_offset=1 +) + +# enable memory savings +pipe.enable_vae_slicing() +pipe.enable_vae_tiling() + +# enable FreeInit +# Refer to the enable_free_init documentation for a full list of configurable parameters +pipe.enable_free_init(method="butterworth", use_fast_sampling=True) + +# run inference +output = pipe( + prompt="a panda playing a guitar, on a boat, in the ocean, high quality", + negative_prompt="bad quality, worse quality", + num_frames=16, + guidance_scale=7.5, + num_inference_steps=20, + generator=torch.Generator("cpu").manual_seed(666), +) + +# disable FreeInit +pipe.disable_free_init() + +frames = output.frames[0] +export_to_gif(frames, "animation.gif") +``` + + + +FreeInit is not really free - the improved quality comes at the cost of extra computation. It requires sampling a few extra times depending on the `num_iters` parameter that is set when enabling it. Setting the `use_fast_sampling` parameter to `True` can improve the overall performance (at the cost of lower quality compared to when `use_fast_sampling=False` but still better results than vanilla video generation models). + + + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + + + + + + + + + + +
Without FreeInit enabledWith FreeInit enabled
+ panda playing a guitar +
+ +## Using AnimateLCM + +[AnimateLCM](https://animatelcm.github.io/) is a motion module checkpoint and an [LCM LoRA](https://huggingface.co/docs/diffusers/using-diffusers/inference_with_lcm_lora) that have been created using a consistency learning strategy that decouples the distillation of the image generation priors and the motion generation priors. + +```python +import torch +from diffusers import AnimateDiffPipeline, LCMScheduler, MotionAdapter +from diffusers.utils import export_to_gif + +adapter = MotionAdapter.from_pretrained("wangfuyun/AnimateLCM") +pipe = AnimateDiffPipeline.from_pretrained("emilianJR/epiCRealism", motion_adapter=adapter) +pipe.scheduler = LCMScheduler.from_config(pipe.scheduler.config, beta_schedule="linear") + +pipe.load_lora_weights("wangfuyun/AnimateLCM", weight_name="sd15_lora_beta.safetensors", adapter_name="lcm-lora") + +pipe.enable_vae_slicing() +pipe.enable_model_cpu_offload() + +output = pipe( + prompt="A space rocket with trails of smoke behind it launching into space from the desert, 4k, high resolution", + negative_prompt="bad quality, worse quality, low resolution", + num_frames=16, + guidance_scale=1.5, + num_inference_steps=6, + generator=torch.Generator("cpu").manual_seed(0), +) +frames = output.frames[0] +export_to_gif(frames, "animatelcm.gif") +``` + + + + + +
+ A space rocket, 4K. +
+ A space rocket, 4K +
+ +AnimateLCM is also compatible with existing [Motion LoRAs](https://huggingface.co/collections/dn6/animatediff-motion-loras-654cb8ad732b9e3cf4d3c17e). + +```python +import torch +from diffusers import AnimateDiffPipeline, LCMScheduler, MotionAdapter +from diffusers.utils import export_to_gif + +adapter = MotionAdapter.from_pretrained("wangfuyun/AnimateLCM") +pipe = AnimateDiffPipeline.from_pretrained("emilianJR/epiCRealism", motion_adapter=adapter) +pipe.scheduler = LCMScheduler.from_config(pipe.scheduler.config, beta_schedule="linear") + +pipe.load_lora_weights("wangfuyun/AnimateLCM", weight_name="sd15_lora_beta.safetensors", adapter_name="lcm-lora") +pipe.load_lora_weights("guoyww/animatediff-motion-lora-tilt-up", adapter_name="tilt-up") + +pipe.set_adapters(["lcm-lora", "tilt-up"], [1.0, 0.8]) +pipe.enable_vae_slicing() +pipe.enable_model_cpu_offload() + +output = pipe( + prompt="A space rocket with trails of smoke behind it launching into space from the desert, 4k, high resolution", + negative_prompt="bad quality, worse quality, low resolution", + num_frames=16, + guidance_scale=1.5, + num_inference_steps=6, + generator=torch.Generator("cpu").manual_seed(0), +) +frames = output.frames[0] +export_to_gif(frames, "animatelcm-motion-lora.gif") +``` + + + + + +
+ A space rocket, 4K. +
+ A space rocket, 4K +
+ +## Using FreeNoise + +[FreeNoise: Tuning-Free Longer Video Diffusion via Noise Rescheduling](https://huggingface.co/papers/2310.15169) by Haonan Qiu, Menghan Xia, Yong Zhang, Yingqing He, Xintao Wang, Ying Shan, Ziwei Liu. + +FreeNoise is a sampling mechanism that can generate longer videos with short-video generation models by employing noise-rescheduling, temporal attention over sliding windows, and weighted averaging of latent frames. It also can be used with multiple prompts to allow for interpolated video generations. More details are available in the paper. + +The currently supported AnimateDiff pipelines that can be used with FreeNoise are: +- [`AnimateDiffPipeline`] +- [`AnimateDiffControlNetPipeline`] +- [`AnimateDiffVideoToVideoPipeline`] +- [`AnimateDiffVideoToVideoControlNetPipeline`] + +In order to use FreeNoise, a single line needs to be added to the inference code after loading your pipelines. + +```diff ++ pipe.enable_free_noise() +``` + +After this, either a single prompt could be used, or multiple prompts can be passed as a dictionary of integer-string pairs. The integer keys of the dictionary correspond to the frame index at which the influence of that prompt would be maximum. Each frame index should map to a single string prompt. The prompts for intermediate frame indices, that are not passed in the dictionary, are created by interpolating between the frame prompts that are passed. By default, simple linear interpolation is used. However, you can customize this behaviour with a callback to the `prompt_interpolation_callback` parameter when enabling FreeNoise. + +Full example: + +```python +import torch +from diffusers import AutoencoderKL, AnimateDiffPipeline, LCMScheduler, MotionAdapter +from diffusers.utils import export_to_video, load_image + +# Load pipeline +dtype = torch.float16 +motion_adapter = MotionAdapter.from_pretrained("wangfuyun/AnimateLCM", torch_dtype=dtype) +vae = AutoencoderKL.from_pretrained("stabilityai/sd-vae-ft-mse", torch_dtype=dtype) + +pipe = AnimateDiffPipeline.from_pretrained("emilianJR/epiCRealism", motion_adapter=motion_adapter, vae=vae, torch_dtype=dtype) +pipe.scheduler = LCMScheduler.from_config(pipe.scheduler.config, beta_schedule="linear") + +pipe.load_lora_weights( + "wangfuyun/AnimateLCM", weight_name="AnimateLCM_sd15_t2v_lora.safetensors", adapter_name="lcm_lora" +) +pipe.set_adapters(["lcm_lora"], [0.8]) + +# Enable FreeNoise for long prompt generation +pipe.enable_free_noise(context_length=16, context_stride=4) +pipe.to("cuda") + +# Can be a single prompt, or a dictionary with frame timesteps +prompt = { + 0: "A caterpillar on a leaf, high quality, photorealistic", + 40: "A caterpillar transforming into a cocoon, on a leaf, near flowers, photorealistic", + 80: "A cocoon on a leaf, flowers in the background, photorealistic", + 120: "A cocoon maturing and a butterfly being born, flowers and leaves visible in the background, photorealistic", + 160: "A beautiful butterfly, vibrant colors, sitting on a leaf, flowers in the background, photorealistic", + 200: "A beautiful butterfly, flying away in a forest, photorealistic", + 240: "A cyberpunk butterfly, neon lights, glowing", +} +negative_prompt = "bad quality, worst quality, jpeg artifacts" + +# Run inference +output = pipe( + prompt=prompt, + negative_prompt=negative_prompt, + num_frames=256, + guidance_scale=2.5, + num_inference_steps=10, + generator=torch.Generator("cpu").manual_seed(0), +) + +# Save video +frames = output.frames[0] +export_to_video(frames, "output.mp4", fps=16) +``` + +### FreeNoise memory savings + +Since FreeNoise processes multiple frames together, there are parts in the modeling where the memory required exceeds that available on normal consumer GPUs. The main memory bottlenecks that we identified are spatial and temporal attention blocks, upsampling and downsampling blocks, resnet blocks and feed-forward layers. Since most of these blocks operate effectively only on the channel/embedding dimension, one can perform chunked inference across the batch dimensions. The batch dimension in AnimateDiff are either spatial (`[B x F, H x W, C]`) or temporal (`B x H x W, F, C`) in nature (note that it may seem counter-intuitive, but the batch dimension here are correct, because spatial blocks process across the `B x F` dimension while the temporal blocks process across the `B x H x W` dimension). We introduce a `SplitInferenceModule` that makes it easier to chunk across any dimension and perform inference. This saves a lot of memory but comes at the cost of requiring more time for inference. + +```diff +# Load pipeline and adapters +# ... ++ pipe.enable_free_noise_split_inference() ++ pipe.unet.enable_forward_chunking(16) +``` + +The call to `pipe.enable_free_noise_split_inference` method accepts two parameters: `spatial_split_size` (defaults to `256`) and `temporal_split_size` (defaults to `16`). These can be configured based on how much VRAM you have available. A lower split size results in lower memory usage but slower inference, whereas a larger split size results in faster inference at the cost of more memory. + +## Using `from_single_file` with the MotionAdapter + +`diffusers>=0.30.0` supports loading the AnimateDiff checkpoints into the `MotionAdapter` in their original format via `from_single_file` + +```python +from diffusers import MotionAdapter + +ckpt_path = "https://huggingface.co/Lightricks/LongAnimateDiff/blob/main/lt_long_mm_32_frames.ckpt" + +adapter = MotionAdapter.from_single_file(ckpt_path, torch_dtype=torch.float16) +pipe = AnimateDiffPipeline.from_pretrained("emilianJR/epiCRealism", motion_adapter=adapter) +``` + +## AnimateDiffPipeline + +[[autodoc]] AnimateDiffPipeline + - all + - __call__ + +## AnimateDiffControlNetPipeline + +[[autodoc]] AnimateDiffControlNetPipeline + - all + - __call__ + +## AnimateDiffSparseControlNetPipeline + +[[autodoc]] AnimateDiffSparseControlNetPipeline + - all + - __call__ + +## AnimateDiffSDXLPipeline + +[[autodoc]] AnimateDiffSDXLPipeline + - all + - __call__ + +## AnimateDiffVideoToVideoPipeline + +[[autodoc]] AnimateDiffVideoToVideoPipeline + - all + - __call__ + +## AnimateDiffVideoToVideoControlNetPipeline + +[[autodoc]] AnimateDiffVideoToVideoControlNetPipeline + - all + - __call__ + +## AnimateDiffPipelineOutput + +[[autodoc]] pipelines.animatediff.AnimateDiffPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/attend_and_excite.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/attend_and_excite.md new file mode 100644 index 0000000000000000000000000000000000000000..953ab1bb728884a304d409054e3faa0b33aeb899 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/attend_and_excite.md @@ -0,0 +1,37 @@ + + +# Attend-and-Excite + +Attend-and-Excite for Stable Diffusion was proposed in [Attend-and-Excite: Attention-Based Semantic Guidance for Text-to-Image Diffusion Models](https://attendandexcite.github.io/Attend-and-Excite/) and provides textual attention control over image generation. + +The abstract from the paper is: + +*Recent text-to-image generative models have demonstrated an unparalleled ability to generate diverse and creative imagery guided by a target text prompt. While revolutionary, current state-of-the-art diffusion models may still fail in generating images that fully convey the semantics in the given text prompt. We analyze the publicly available Stable Diffusion model and assess the existence of catastrophic neglect, where the model fails to generate one or more of the subjects from the input prompt. Moreover, we find that in some cases the model also fails to correctly bind attributes (e.g., colors) to their corresponding subjects. To help mitigate these failure cases, we introduce the concept of Generative Semantic Nursing (GSN), where we seek to intervene in the generative process on the fly during inference time to improve the faithfulness of the generated images. Using an attention-based formulation of GSN, dubbed Attend-and-Excite, we guide the model to refine the cross-attention units to attend to all subject tokens in the text prompt and strengthen - or excite - their activations, encouraging the model to generate all subjects described in the text prompt. We compare our approach to alternative approaches and demonstrate that it conveys the desired concepts more faithfully across a range of text prompts.* + +You can find additional information about Attend-and-Excite on the [project page](https://attendandexcite.github.io/Attend-and-Excite/), the [original codebase](https://github.com/AttendAndExcite/Attend-and-Excite), or try it out in a [demo](https://huggingface.co/spaces/AttendAndExcite/Attend-and-Excite). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## StableDiffusionAttendAndExcitePipeline + +[[autodoc]] StableDiffusionAttendAndExcitePipeline + - all + - __call__ + +## StableDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/audioldm.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/audioldm.md new file mode 100644 index 0000000000000000000000000000000000000000..02fe2c779eee5ef9b464f0dfa61e1ffa9b9a077f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/audioldm.md @@ -0,0 +1,50 @@ + + +# AudioLDM + +AudioLDM was proposed in [AudioLDM: Text-to-Audio Generation with Latent Diffusion Models](https://huggingface.co/papers/2301.12503) by Haohe Liu et al. Inspired by [Stable Diffusion](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion/overview), AudioLDM +is a text-to-audio _latent diffusion model (LDM)_ that learns continuous audio representations from [CLAP](https://huggingface.co/docs/transformers/main/model_doc/clap) +latents. AudioLDM takes a text prompt as input and predicts the corresponding audio. It can generate text-conditional +sound effects, human speech and music. + +The abstract from the paper is: + +*Text-to-audio (TTA) system has recently gained attention for its ability to synthesize general audio based on text descriptions. However, previous studies in TTA have limited generation quality with high computational costs. In this study, we propose AudioLDM, a TTA system that is built on a latent space to learn the continuous audio representations from contrastive language-audio pretraining (CLAP) latents. The pretrained CLAP models enable us to train LDMs with audio embedding while providing text embedding as a condition during sampling. By learning the latent representations of audio signals and their compositions without modeling the cross-modal relationship, AudioLDM is advantageous in both generation quality and computational efficiency. Trained on AudioCaps with a single GPU, AudioLDM achieves state-of-the-art TTA performance measured by both objective and subjective metrics (e.g., frechet distance). Moreover, AudioLDM is the first TTA system that enables various text-guided audio manipulations (e.g., style transfer) in a zero-shot fashion. Our implementation and demos are available at [this https URL](https://audioldm.github.io/).* + +The original codebase can be found at [haoheliu/AudioLDM](https://github.com/haoheliu/AudioLDM). + +## Tips + +When constructing a prompt, keep in mind: + +* Descriptive prompt inputs work best; you can use adjectives to describe the sound (for example, "high quality" or "clear") and make the prompt context specific (for example, "water stream in a forest" instead of "stream"). +* It's best to use general terms like "cat" or "dog" instead of specific names or abstract objects the model may not be familiar with. + +During inference: + +* The _quality_ of the predicted audio sample can be controlled by the `num_inference_steps` argument; higher steps give higher quality audio at the expense of slower inference. +* The _length_ of the predicted audio sample can be controlled by varying the `audio_length_in_s` argument. + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## AudioLDMPipeline +[[autodoc]] AudioLDMPipeline + - all + - __call__ + +## AudioPipelineOutput +[[autodoc]] pipelines.AudioPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/audioldm2.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/audioldm2.md new file mode 100644 index 0000000000000000000000000000000000000000..b10696da0fba31f54f42a865c037707dc1845310 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/audioldm2.md @@ -0,0 +1,81 @@ + + +# AudioLDM 2 + +AudioLDM 2 was proposed in [AudioLDM 2: Learning Holistic Audio Generation with Self-supervised Pretraining](https://huggingface.co/papers/2308.05734) by Haohe Liu et al. AudioLDM 2 takes a text prompt as input and predicts the corresponding audio. It can generate text-conditional sound effects, human speech and music. + +Inspired by [Stable Diffusion](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion/overview), AudioLDM 2 is a text-to-audio _latent diffusion model (LDM)_ that learns continuous audio representations from text embeddings. Two text encoder models are used to compute the text embeddings from a prompt input: the text-branch of [CLAP](https://huggingface.co/docs/transformers/main/en/model_doc/clap) and the encoder of [Flan-T5](https://huggingface.co/docs/transformers/main/en/model_doc/flan-t5). These text embeddings are then projected to a shared embedding space by an [AudioLDM2ProjectionModel](https://huggingface.co/docs/diffusers/main/api/pipelines/audioldm2#diffusers.AudioLDM2ProjectionModel). A [GPT2](https://huggingface.co/docs/transformers/main/en/model_doc/gpt2) _language model (LM)_ is used to auto-regressively predict eight new embedding vectors, conditional on the projected CLAP and Flan-T5 embeddings. The generated embedding vectors and Flan-T5 text embeddings are used as cross-attention conditioning in the LDM. The [UNet](https://huggingface.co/docs/diffusers/main/en/api/pipelines/audioldm2#diffusers.AudioLDM2UNet2DConditionModel) of AudioLDM 2 is unique in the sense that it takes **two** cross-attention embeddings, as opposed to one cross-attention conditioning, as in most other LDMs. + +The abstract of the paper is the following: + +*Although audio generation shares commonalities across different types of audio, such as speech, music, and sound effects, designing models for each type requires careful consideration of specific objectives and biases that can significantly differ from those of other types. To bring us closer to a unified perspective of audio generation, this paper proposes a framework that utilizes the same learning method for speech, music, and sound effect generation. Our framework introduces a general representation of audio, called "language of audio" (LOA). Any audio can be translated into LOA based on AudioMAE, a self-supervised pre-trained representation learning model. In the generation process, we translate any modalities into LOA by using a GPT-2 model, and we perform self-supervised audio generation learning with a latent diffusion model conditioned on LOA. The proposed framework naturally brings advantages such as in-context learning abilities and reusable self-supervised pretrained AudioMAE and latent diffusion models. Experiments on the major benchmarks of text-to-audio, text-to-music, and text-to-speech demonstrate state-of-the-art or competitive performance against previous approaches. Our code, pretrained model, and demo are available at [this https URL](https://audioldm.github.io/audioldm2).* + +This pipeline was contributed by [sanchit-gandhi](https://huggingface.co/sanchit-gandhi) and [Nguyễn Công Tú Anh](https://github.com/tuanh123789). The original codebase can be +found at [haoheliu/audioldm2](https://github.com/haoheliu/audioldm2). + +## Tips + +### Choosing a checkpoint + +AudioLDM2 comes in three variants. Two of these checkpoints are applicable to the general task of text-to-audio generation. The third checkpoint is trained exclusively on text-to-music generation. + +All checkpoints share the same model size for the text encoders and VAE. They differ in the size and depth of the UNet. +See table below for details on the three checkpoints: + +| Checkpoint | Task | UNet Model Size | Total Model Size | Training Data / h | +|-----------------------------------------------------------------|---------------|-----------------|------------------|-------------------| +| [audioldm2](https://huggingface.co/cvssp/audioldm2) | Text-to-audio | 350M | 1.1B | 1150k | +| [audioldm2-large](https://huggingface.co/cvssp/audioldm2-large) | Text-to-audio | 750M | 1.5B | 1150k | +| [audioldm2-music](https://huggingface.co/cvssp/audioldm2-music) | Text-to-music | 350M | 1.1B | 665k | +| [audioldm2-gigaspeech](https://huggingface.co/anhnct/audioldm2_gigaspeech) | Text-to-speech | 350M | 1.1B |10k | +| [audioldm2-ljspeech](https://huggingface.co/anhnct/audioldm2_ljspeech) | Text-to-speech | 350M | 1.1B | | + +### Constructing a prompt + +* Descriptive prompt inputs work best: use adjectives to describe the sound (e.g. "high quality" or "clear") and make the prompt context specific (e.g. "water stream in a forest" instead of "stream"). +* It's best to use general terms like "cat" or "dog" instead of specific names or abstract objects the model may not be familiar with. +* Using a **negative prompt** can significantly improve the quality of the generated waveform, by guiding the generation away from terms that correspond to poor quality audio. Try using a negative prompt of "Low quality." + +### Controlling inference + +* The _quality_ of the predicted audio sample can be controlled by the `num_inference_steps` argument; higher steps give higher quality audio at the expense of slower inference. +* The _length_ of the predicted audio sample can be controlled by varying the `audio_length_in_s` argument. + +### Evaluating generated waveforms: + +* The quality of the generated waveforms can vary significantly based on the seed. Try generating with different seeds until you find a satisfactory generation. +* Multiple waveforms can be generated in one go: set `num_waveforms_per_prompt` to a value greater than 1. Automatic scoring will be performed between the generated waveforms and prompt text, and the audios ranked from best to worst accordingly. + +The following example demonstrates how to construct good music and speech generation using the aforementioned tips: [example](https://huggingface.co/docs/diffusers/main/en/api/pipelines/audioldm2#diffusers.AudioLDM2Pipeline.__call__.example). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## AudioLDM2Pipeline +[[autodoc]] AudioLDM2Pipeline + - all + - __call__ + +## AudioLDM2ProjectionModel +[[autodoc]] AudioLDM2ProjectionModel + - forward + +## AudioLDM2UNet2DConditionModel +[[autodoc]] AudioLDM2UNet2DConditionModel + - forward + +## AudioPipelineOutput +[[autodoc]] pipelines.AudioPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/aura_flow.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/aura_flow.md new file mode 100644 index 0000000000000000000000000000000000000000..52c74a3ac549631f4def213606eb05289ec2300a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/aura_flow.md @@ -0,0 +1,113 @@ + + +# AuraFlow + +AuraFlow is inspired by [Stable Diffusion 3](../pipelines/stable_diffusion/stable_diffusion_3) and is by far the largest text-to-image generation model that comes with an Apache 2.0 license. This model achieves state-of-the-art results on the [GenEval](https://github.com/djghosh13/geneval) benchmark. + +It was developed by the Fal team and more details about it can be found in [this blog post](https://blog.fal.ai/auraflow/). + + + +AuraFlow can be quite expensive to run on consumer hardware devices. However, you can perform a suite of optimizations to run it faster and in a more memory-friendly manner. Check out [this section](https://huggingface.co/blog/sd3#memory-optimizations-for-sd3) for more details. + + + +## Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`AuraFlowPipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, AuraFlowTransformer2DModel, AuraFlowPipeline +from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel + +quant_config = BitsAndBytesConfig(load_in_8bit=True) +text_encoder_8bit = T5EncoderModel.from_pretrained( + "fal/AuraFlow", + subfolder="text_encoder", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = AuraFlowTransformer2DModel.from_pretrained( + "fal/AuraFlow", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +pipeline = AuraFlowPipeline.from_pretrained( + "fal/AuraFlow", + text_encoder=text_encoder_8bit, + transformer=transformer_8bit, + torch_dtype=torch.float16, + device_map="balanced", +) + +prompt = "a tiny astronaut hatching from an egg on the moon" +image = pipeline(prompt).images[0] +image.save("auraflow.png") +``` + +Loading [GGUF checkpoints](https://huggingface.co/docs/diffusers/quantization/gguf) are also supported: + +```py +import torch +from diffusers import ( + AuraFlowPipeline, + GGUFQuantizationConfig, + AuraFlowTransformer2DModel, +) + +transformer = AuraFlowTransformer2DModel.from_single_file( + "https://huggingface.co/city96/AuraFlow-v0.3-gguf/blob/main/aura_flow_0.3-Q2_K.gguf", + quantization_config=GGUFQuantizationConfig(compute_dtype=torch.bfloat16), + torch_dtype=torch.bfloat16, +) + +pipeline = AuraFlowPipeline.from_pretrained( + "fal/AuraFlow-v0.3", + transformer=transformer, + torch_dtype=torch.bfloat16, +) + +prompt = "a cute pony in a field of flowers" +image = pipeline(prompt).images[0] +image.save("auraflow.png") +``` + +## Support for `torch.compile()` + +AuraFlow can be compiled with `torch.compile()` to speed up inference latency even for different resolutions. First, install PyTorch nightly following the instructions from [here](https://pytorch.org/). The snippet below shows the changes needed to enable this: + +```diff ++ torch.fx.experimental._config.use_duck_shape = False ++ pipeline.transformer = torch.compile( + pipeline.transformer, fullgraph=True, dynamic=True +) +``` + +Specifying `use_duck_shape` to be `False` instructs the compiler if it should use the same symbolic variable to represent input sizes that are the same. For more details, check out [this comment](https://github.com/huggingface/diffusers/pull/11327#discussion_r2047659790). + +This enables from 100% (on low resolutions) to a 30% (on 1536x1536 resolution) speed improvements. + +Thanks to [AstraliteHeart](https://github.com/huggingface/diffusers/pull/11297/) who helped us rewrite the [`AuraFlowTransformer2DModel`] class so that the above works for different resolutions ([PR](https://github.com/huggingface/diffusers/pull/11297/)). + +## AuraFlowPipeline + +[[autodoc]] AuraFlowPipeline + - all + - __call__ \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/auto_pipeline.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/auto_pipeline.md new file mode 100644 index 0000000000000000000000000000000000000000..f30bf7873c146aa1327ec73dac39eac1cde67c7d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/auto_pipeline.md @@ -0,0 +1,39 @@ + + +# AutoPipeline + +The `AutoPipeline` is designed to make it easy to load a checkpoint for a task without needing to know the specific pipeline class. Based on the task, the `AutoPipeline` automatically retrieves the correct pipeline class from the checkpoint `model_index.json` file. + +> [!TIP] +> Check out the [AutoPipeline](../../tutorials/autopipeline) tutorial to learn how to use this API! + +## AutoPipelineForText2Image + +[[autodoc]] AutoPipelineForText2Image + - all + - from_pretrained + - from_pipe + +## AutoPipelineForImage2Image + +[[autodoc]] AutoPipelineForImage2Image + - all + - from_pretrained + - from_pipe + +## AutoPipelineForInpainting + +[[autodoc]] AutoPipelineForInpainting + - all + - from_pretrained + - from_pipe diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/blip_diffusion.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/blip_diffusion.md new file mode 100644 index 0000000000000000000000000000000000000000..8db329ee2b081116d996c0ee778deadbfd1438ed --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/blip_diffusion.md @@ -0,0 +1,41 @@ + + +# BLIP-Diffusion + +BLIP-Diffusion was proposed in [BLIP-Diffusion: Pre-trained Subject Representation for Controllable Text-to-Image Generation and Editing](https://huggingface.co/papers/2305.14720). It enables zero-shot subject-driven generation and control-guided zero-shot generation. + + +The abstract from the paper is: + +*Subject-driven text-to-image generation models create novel renditions of an input subject based on text prompts. Existing models suffer from lengthy fine-tuning and difficulties preserving the subject fidelity. To overcome these limitations, we introduce BLIP-Diffusion, a new subject-driven image generation model that supports multimodal control which consumes inputs of subject images and text prompts. Unlike other subject-driven generation models, BLIP-Diffusion introduces a new multimodal encoder which is pre-trained to provide subject representation. We first pre-train the multimodal encoder following BLIP-2 to produce visual representation aligned with the text. Then we design a subject representation learning task which enables a diffusion model to leverage such visual representation and generates new subject renditions. Compared with previous methods such as DreamBooth, our model enables zero-shot subject-driven generation, and efficient fine-tuning for customized subject with up to 20x speedup. We also demonstrate that BLIP-Diffusion can be flexibly combined with existing techniques such as ControlNet and prompt-to-prompt to enable novel subject-driven generation and editing applications. Project page at [this https URL](https://dxli94.github.io/BLIP-Diffusion-website/).* + +The original codebase can be found at [salesforce/LAVIS](https://github.com/salesforce/LAVIS/tree/main/projects/blip-diffusion). You can find the official BLIP-Diffusion checkpoints under the [hf.co/SalesForce](https://hf.co/SalesForce) organization. + +`BlipDiffusionPipeline` and `BlipDiffusionControlNetPipeline` were contributed by [`ayushtues`](https://github.com/ayushtues/). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + + +## BlipDiffusionPipeline +[[autodoc]] BlipDiffusionPipeline + - all + - __call__ + +## BlipDiffusionControlNetPipeline +[[autodoc]] BlipDiffusionControlNetPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/cogvideox.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/cogvideox.md new file mode 100644 index 0000000000000000000000000000000000000000..53ef93246fd1b6c0252207afca6c9ea9b30b3a05 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/cogvideox.md @@ -0,0 +1,186 @@ + + +# CogVideoX + +
+ LoRA +
+ +[CogVideoX: Text-to-Video Diffusion Models with An Expert Transformer](https://huggingface.co/papers/2408.06072) from Tsinghua University & ZhipuAI, by Zhuoyi Yang, Jiayan Teng, Wendi Zheng, Ming Ding, Shiyu Huang, Jiazheng Xu, Yuanming Yang, Wenyi Hong, Xiaohan Zhang, Guanyu Feng, Da Yin, Xiaotao Gu, Yuxuan Zhang, Weihan Wang, Yean Cheng, Ting Liu, Bin Xu, Yuxiao Dong, Jie Tang. + +The abstract from the paper is: + +*We introduce CogVideoX, a large-scale diffusion transformer model designed for generating videos based on text prompts. To efficently model video data, we propose to levearge a 3D Variational Autoencoder (VAE) to compresses videos along both spatial and temporal dimensions. To improve the text-video alignment, we propose an expert transformer with the expert adaptive LayerNorm to facilitate the deep fusion between the two modalities. By employing a progressive training technique, CogVideoX is adept at producing coherent, long-duration videos characterized by significant motion. In addition, we develop an effectively text-video data processing pipeline that includes various data preprocessing strategies and a video captioning method. It significantly helps enhance the performance of CogVideoX, improving both generation quality and semantic alignment. Results show that CogVideoX demonstrates state-of-the-art performance across both multiple machine metrics and human evaluations. The model weight of CogVideoX-2B is publicly available at https://github.com/THUDM/CogVideo.* + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +This pipeline was contributed by [zRzRzRzRzRzRzR](https://github.com/zRzRzRzRzRzRzR). The original codebase can be found [here](https://huggingface.co/THUDM). The original weights can be found under [hf.co/THUDM](https://huggingface.co/THUDM). + +There are three official CogVideoX checkpoints for text-to-video and video-to-video. + +| checkpoints | recommended inference dtype | +|:---:|:---:| +| [`THUDM/CogVideoX-2b`](https://huggingface.co/THUDM/CogVideoX-2b) | torch.float16 | +| [`THUDM/CogVideoX-5b`](https://huggingface.co/THUDM/CogVideoX-5b) | torch.bfloat16 | +| [`THUDM/CogVideoX1.5-5b`](https://huggingface.co/THUDM/CogVideoX1.5-5b) | torch.bfloat16 | + +There are two official CogVideoX checkpoints available for image-to-video. + +| checkpoints | recommended inference dtype | +|:---:|:---:| +| [`THUDM/CogVideoX-5b-I2V`](https://huggingface.co/THUDM/CogVideoX-5b-I2V) | torch.bfloat16 | +| [`THUDM/CogVideoX-1.5-5b-I2V`](https://huggingface.co/THUDM/CogVideoX-1.5-5b-I2V) | torch.bfloat16 | + +For the CogVideoX 1.5 series: +- Text-to-video (T2V) works best at a resolution of 1360x768 because it was trained with that specific resolution. +- Image-to-video (I2V) works for multiple resolutions. The width can vary from 768 to 1360, but the height must be 768. The height/width must be divisible by 16. +- Both T2V and I2V models support generation with 81 and 161 frames and work best at this value. Exporting videos at 16 FPS is recommended. + +There are two official CogVideoX checkpoints that support pose controllable generation (by the [Alibaba-PAI](https://huggingface.co/alibaba-pai) team). + +| checkpoints | recommended inference dtype | +|:---:|:---:| +| [`alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose`](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-2b-Pose) | torch.bfloat16 | +| [`alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose`](https://huggingface.co/alibaba-pai/CogVideoX-Fun-V1.1-5b-Pose) | torch.bfloat16 | + +## Inference + +Use [`torch.compile`](https://huggingface.co/docs/diffusers/main/en/tutorials/fast_diffusion#torchcompile) to reduce the inference latency. + +First, load the pipeline: + +```python +import torch +from diffusers import CogVideoXPipeline, CogVideoXImageToVideoPipeline +from diffusers.utils import export_to_video,load_image +pipe = CogVideoXPipeline.from_pretrained("THUDM/CogVideoX-5b").to("cuda") # or "THUDM/CogVideoX-2b" +``` + +If you are using the image-to-video pipeline, load it as follows: + +```python +pipe = CogVideoXImageToVideoPipeline.from_pretrained("THUDM/CogVideoX-5b-I2V").to("cuda") +``` + +Then change the memory layout of the pipelines `transformer` component to `torch.channels_last`: + +```python +pipe.transformer.to(memory_format=torch.channels_last) +``` + +Compile the components and run inference: + +```python +pipe.transformer = torch.compile(pipeline.transformer, mode="max-autotune", fullgraph=True) + +# CogVideoX works well with long and well-described prompts +prompt = "A panda, dressed in a small, red jacket and a tiny hat, sits on a wooden stool in a serene bamboo forest. The panda's fluffy paws strum a miniature acoustic guitar, producing soft, melodic tunes. Nearby, a few other pandas gather, watching curiously and some clapping in rhythm. Sunlight filters through the tall bamboo, casting a gentle glow on the scene. The panda's face is expressive, showing concentration and joy as it plays. The background includes a small, flowing stream and vibrant green foliage, enhancing the peaceful and magical atmosphere of this unique musical performance." +video = pipe(prompt=prompt, guidance_scale=6, num_inference_steps=50).frames[0] +``` + +The [T2V benchmark](https://gist.github.com/a-r-r-o-w/5183d75e452a368fd17448fcc810bd3f) results on an 80GB A100 machine are: + +``` +Without torch.compile(): Average inference time: 96.89 seconds. +With torch.compile(): Average inference time: 76.27 seconds. +``` + +### Memory optimization + +CogVideoX-2b requires about 19 GB of GPU memory to decode 49 frames (6 seconds of video at 8 FPS) with output resolution 720x480 (W x H), which makes it not possible to run on consumer GPUs or free-tier T4 Colab. The following memory optimizations could be used to reduce the memory footprint. For replication, you can refer to [this](https://gist.github.com/a-r-r-o-w/3959a03f15be5c9bd1fe545b09dfcc93) script. + +- `pipe.enable_model_cpu_offload()`: + - Without enabling cpu offloading, memory usage is `33 GB` + - With enabling cpu offloading, memory usage is `19 GB` +- `pipe.enable_sequential_cpu_offload()`: + - Similar to `enable_model_cpu_offload` but can significantly reduce memory usage at the cost of slow inference + - When enabled, memory usage is under `4 GB` +- `pipe.vae.enable_tiling()`: + - With enabling cpu offloading and tiling, memory usage is `11 GB` +- `pipe.vae.enable_slicing()` + +## Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`CogVideoXPipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, CogVideoXTransformer3DModel, CogVideoXPipeline +from diffusers.utils import export_to_video +from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel + +quant_config = BitsAndBytesConfig(load_in_8bit=True) +text_encoder_8bit = T5EncoderModel.from_pretrained( + "THUDM/CogVideoX-2b", + subfolder="text_encoder", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = CogVideoXTransformer3DModel.from_pretrained( + "THUDM/CogVideoX-2b", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +pipeline = CogVideoXPipeline.from_pretrained( + "THUDM/CogVideoX-2b", + text_encoder=text_encoder_8bit, + transformer=transformer_8bit, + torch_dtype=torch.float16, + device_map="balanced", +) + +prompt = "A detailed wooden toy ship with intricately carved masts and sails is seen gliding smoothly over a plush, blue carpet that mimics the waves of the sea. The ship's hull is painted a rich brown, with tiny windows. The carpet, soft and textured, provides a perfect backdrop, resembling an oceanic expanse. Surrounding the ship are various other toys and children's items, hinting at a playful environment. The scene captures the innocence and imagination of childhood, with the toy ship's journey symbolizing endless adventures in a whimsical, indoor setting." +video = pipeline(prompt=prompt, guidance_scale=6, num_inference_steps=50).frames[0] +export_to_video(video, "ship.mp4", fps=8) +``` + +## CogVideoXPipeline + +[[autodoc]] CogVideoXPipeline + - all + - __call__ + +## CogVideoXImageToVideoPipeline + +[[autodoc]] CogVideoXImageToVideoPipeline + - all + - __call__ + +## CogVideoXVideoToVideoPipeline + +[[autodoc]] CogVideoXVideoToVideoPipeline + - all + - __call__ + +## CogVideoXFunControlPipeline + +[[autodoc]] CogVideoXFunControlPipeline + - all + - __call__ + +## CogVideoXPipelineOutput + +[[autodoc]] pipelines.cogvideo.pipeline_output.CogVideoXPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/cogview3.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/cogview3.md new file mode 100644 index 0000000000000000000000000000000000000000..277edca4cf334ec0b6948f8ff3be1f897a8db0bb --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/cogview3.md @@ -0,0 +1,40 @@ + + +# CogView3Plus + +[CogView3: Finer and Faster Text-to-Image Generation via Relay Diffusion](https://huggingface.co/papers/2403.05121) from Tsinghua University & ZhipuAI, by Wendi Zheng, Jiayan Teng, Zhuoyi Yang, Weihan Wang, Jidong Chen, Xiaotao Gu, Yuxiao Dong, Ming Ding, Jie Tang. + +The abstract from the paper is: + +*Recent advancements in text-to-image generative systems have been largely driven by diffusion models. However, single-stage text-to-image diffusion models still face challenges, in terms of computational efficiency and the refinement of image details. To tackle the issue, we propose CogView3, an innovative cascaded framework that enhances the performance of text-to-image diffusion. CogView3 is the first model implementing relay diffusion in the realm of text-to-image generation, executing the task by first creating low-resolution images and subsequently applying relay-based super-resolution. This methodology not only results in competitive text-to-image outputs but also greatly reduces both training and inference costs. Our experimental results demonstrate that CogView3 outperforms SDXL, the current state-of-the-art open-source text-to-image diffusion model, by 77.0% in human evaluations, all while requiring only about 1/2 of the inference time. The distilled variant of CogView3 achieves comparable performance while only utilizing 1/10 of the inference time by SDXL.* + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +This pipeline was contributed by [zRzRzRzRzRzRzR](https://github.com/zRzRzRzRzRzRzR). The original codebase can be found [here](https://huggingface.co/THUDM). The original weights can be found under [hf.co/THUDM](https://huggingface.co/THUDM). + +## CogView3PlusPipeline + +[[autodoc]] CogView3PlusPipeline + - all + - __call__ + +## CogView3PipelineOutput + +[[autodoc]] pipelines.cogview3.pipeline_output.CogView3PipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/cogview4.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/cogview4.md new file mode 100644 index 0000000000000000000000000000000000000000..cc17c3c905fbcc62b644363fe290ea6ab9caaa4a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/cogview4.md @@ -0,0 +1,34 @@ + + +# CogView4 + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +This pipeline was contributed by [zRzRzRzRzRzRzR](https://github.com/zRzRzRzRzRzRzR). The original codebase can be found [here](https://huggingface.co/THUDM). The original weights can be found under [hf.co/THUDM](https://huggingface.co/THUDM). + +## CogView4Pipeline + +[[autodoc]] CogView4Pipeline + - all + - __call__ + +## CogView4PipelineOutput + +[[autodoc]] pipelines.cogview4.pipeline_output.CogView4PipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/consisid.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/consisid.md new file mode 100644 index 0000000000000000000000000000000000000000..928ebc8c817014fefbcd9aa81c469122fbb79794 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/consisid.md @@ -0,0 +1,64 @@ + + +# ConsisID + +
+ LoRA +
+ +[Identity-Preserving Text-to-Video Generation by Frequency Decomposition](https://huggingface.co/papers/2411.17440) from Peking University & University of Rochester & etc, by Shenghai Yuan, Jinfa Huang, Xianyi He, Yunyang Ge, Yujun Shi, Liuhan Chen, Jiebo Luo, Li Yuan. + +The abstract from the paper is: + +*Identity-preserving text-to-video (IPT2V) generation aims to create high-fidelity videos with consistent human identity. It is an important task in video generation but remains an open problem for generative models. This paper pushes the technical frontier of IPT2V in two directions that have not been resolved in the literature: (1) A tuning-free pipeline without tedious case-by-case finetuning, and (2) A frequency-aware heuristic identity-preserving Diffusion Transformer (DiT)-based control scheme. To achieve these goals, we propose **ConsisID**, a tuning-free DiT-based controllable IPT2V model to keep human-**id**entity **consis**tent in the generated video. Inspired by prior findings in frequency analysis of vision/diffusion transformers, it employs identity-control signals in the frequency domain, where facial features can be decomposed into low-frequency global features (e.g., profile, proportions) and high-frequency intrinsic features (e.g., identity markers that remain unaffected by pose changes). First, from a low-frequency perspective, we introduce a global facial extractor, which encodes the reference image and facial key points into a latent space, generating features enriched with low-frequency information. These features are then integrated into the shallow layers of the network to alleviate training challenges associated with DiT. Second, from a high-frequency perspective, we design a local facial extractor to capture high-frequency details and inject them into the transformer blocks, enhancing the model's ability to preserve fine-grained features. To leverage the frequency information for identity preservation, we propose a hierarchical training strategy, transforming a vanilla pre-trained video generation model into an IPT2V model. Extensive experiments demonstrate that our frequency-aware heuristic scheme provides an optimal control solution for DiT-based models. Thanks to this scheme, our **ConsisID** achieves excellent results in generating high-quality, identity-preserving videos, making strides towards more effective IPT2V. The model weight of ConsID is publicly available at https://github.com/PKU-YuanGroup/ConsisID.* + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers.md) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading.md#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +This pipeline was contributed by [SHYuanBest](https://github.com/SHYuanBest). The original codebase can be found [here](https://github.com/PKU-YuanGroup/ConsisID). The original weights can be found under [hf.co/BestWishYsh](https://huggingface.co/BestWishYsh). + +There are two official ConsisID checkpoints for identity-preserving text-to-video. + +| checkpoints | recommended inference dtype | +|:---:|:---:| +| [`BestWishYsh/ConsisID-preview`](https://huggingface.co/BestWishYsh/ConsisID-preview) | torch.bfloat16 | +| [`BestWishYsh/ConsisID-1.5`](https://huggingface.co/BestWishYsh/ConsisID-preview) | torch.bfloat16 | + +### Memory optimization + +ConsisID requires about 44 GB of GPU memory to decode 49 frames (6 seconds of video at 8 FPS) with output resolution 720x480 (W x H), which makes it not possible to run on consumer GPUs or free-tier T4 Colab. The following memory optimizations could be used to reduce the memory footprint. For replication, you can refer to [this](https://gist.github.com/SHYuanBest/bc4207c36f454f9e969adbb50eaf8258) script. + +| Feature (overlay the previous) | Max Memory Allocated | Max Memory Reserved | +| :----------------------------- | :------------------- | :------------------ | +| - | 37 GB | 44 GB | +| enable_model_cpu_offload | 22 GB | 25 GB | +| enable_sequential_cpu_offload | 16 GB | 22 GB | +| vae.enable_slicing | 16 GB | 22 GB | +| vae.enable_tiling | 5 GB | 7 GB | + +## ConsisIDPipeline + +[[autodoc]] ConsisIDPipeline + + - all + - __call__ + +## ConsisIDPipelineOutput + +[[autodoc]] pipelines.consisid.pipeline_output.ConsisIDPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/consistency_models.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/consistency_models.md new file mode 100644 index 0000000000000000000000000000000000000000..680abaad420be71886e6784643db2627a6bfacbf --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/consistency_models.md @@ -0,0 +1,56 @@ + + +# Consistency Models + +Consistency Models were proposed in [Consistency Models](https://huggingface.co/papers/2303.01469) by Yang Song, Prafulla Dhariwal, Mark Chen, and Ilya Sutskever. + +The abstract from the paper is: + +*Diffusion models have significantly advanced the fields of image, audio, and video generation, but they depend on an iterative sampling process that causes slow generation. To overcome this limitation, we propose consistency models, a new family of models that generate high quality samples by directly mapping noise to data. They support fast one-step generation by design, while still allowing multistep sampling to trade compute for sample quality. They also support zero-shot data editing, such as image inpainting, colorization, and super-resolution, without requiring explicit training on these tasks. Consistency models can be trained either by distilling pre-trained diffusion models, or as standalone generative models altogether. Through extensive experiments, we demonstrate that they outperform existing distillation techniques for diffusion models in one- and few-step sampling, achieving the new state-of-the-art FID of 3.55 on CIFAR-10 and 6.20 on ImageNet 64x64 for one-step generation. When trained in isolation, consistency models become a new family of generative models that can outperform existing one-step, non-adversarial generative models on standard benchmarks such as CIFAR-10, ImageNet 64x64 and LSUN 256x256.* + +The original codebase can be found at [openai/consistency_models](https://github.com/openai/consistency_models), and additional checkpoints are available at [openai](https://huggingface.co/openai). + +The pipeline was contributed by [dg845](https://github.com/dg845) and [ayushtues](https://huggingface.co/ayushtues). ❤️ + +## Tips + +For an additional speed-up, use `torch.compile` to generate multiple images in <1 second: + +```diff + import torch + from diffusers import ConsistencyModelPipeline + + device = "cuda" + # Load the cd_bedroom256_lpips checkpoint. + model_id_or_path = "openai/diffusers-cd_bedroom256_lpips" + pipe = ConsistencyModelPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16) + pipe.to(device) + ++ pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True) + + # Multistep sampling + # Timesteps can be explicitly specified; the particular timesteps below are from the original GitHub repo: + # https://github.com/openai/consistency_models/blob/main/scripts/launch.sh#L83 + for _ in range(10): + image = pipe(timesteps=[17, 0]).images[0] + image.show() +``` + + +## ConsistencyModelPipeline +[[autodoc]] ConsistencyModelPipeline + - all + - __call__ + +## ImagePipelineOutput +[[autodoc]] pipelines.ImagePipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/control_flux_inpaint.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/control_flux_inpaint.md new file mode 100644 index 0000000000000000000000000000000000000000..3e8edb498766560afb3c912e121a891ddedcb17d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/control_flux_inpaint.md @@ -0,0 +1,93 @@ + + +# FluxControlInpaint + +
+ LoRA +
+ +FluxControlInpaintPipeline is an implementation of Inpainting for Flux.1 Depth/Canny models. It is a pipeline that allows you to inpaint images using the Flux.1 Depth/Canny models. The pipeline takes an image and a mask as input and returns the inpainted image. + +FLUX.1 Depth and Canny [dev] is a 12 billion parameter rectified flow transformer capable of generating an image based on a text description while following the structure of a given input image. **This is not a ControlNet model**. + +| Control type | Developer | Link | +| -------- | ---------- | ---- | +| Depth | [Black Forest Labs](https://huggingface.co/black-forest-labs) | [Link](https://huggingface.co/black-forest-labs/FLUX.1-Depth-dev) | +| Canny | [Black Forest Labs](https://huggingface.co/black-forest-labs) | [Link](https://huggingface.co/black-forest-labs/FLUX.1-Canny-dev) | + + + + +Flux can be quite expensive to run on consumer hardware devices. However, you can perform a suite of optimizations to run it faster and in a more memory-friendly manner. Check out [this section](https://huggingface.co/blog/sd3#memory-optimizations-for-sd3) for more details. Additionally, Flux can benefit from quantization for memory efficiency with a trade-off in inference latency. Refer to [this blog post](https://huggingface.co/blog/quanto-diffusers) to learn more. For an exhaustive list of resources, check out [this gist](https://gist.github.com/sayakpaul/b664605caf0aa3bf8585ab109dd5ac9c). + + + +```python +import torch +from diffusers import FluxControlInpaintPipeline +from diffusers.models.transformers import FluxTransformer2DModel +from transformers import T5EncoderModel +from diffusers.utils import load_image, make_image_grid +from image_gen_aux import DepthPreprocessor # https://github.com/huggingface/image_gen_aux +from PIL import Image +import numpy as np + +pipe = FluxControlInpaintPipeline.from_pretrained( + "black-forest-labs/FLUX.1-Depth-dev", + torch_dtype=torch.bfloat16, +) +# use following lines if you have GPU constraints +# --------------------------------------------------------------- +transformer = FluxTransformer2DModel.from_pretrained( + "sayakpaul/FLUX.1-Depth-dev-nf4", subfolder="transformer", torch_dtype=torch.bfloat16 +) +text_encoder_2 = T5EncoderModel.from_pretrained( + "sayakpaul/FLUX.1-Depth-dev-nf4", subfolder="text_encoder_2", torch_dtype=torch.bfloat16 +) +pipe.transformer = transformer +pipe.text_encoder_2 = text_encoder_2 +pipe.enable_model_cpu_offload() +# --------------------------------------------------------------- +pipe.to("cuda") + +prompt = "a blue robot singing opera with human-like expressions" +image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/robot.png") + +head_mask = np.zeros_like(image) +head_mask[65:580,300:642] = 255 +mask_image = Image.fromarray(head_mask) + +processor = DepthPreprocessor.from_pretrained("LiheYoung/depth-anything-large-hf") +control_image = processor(image)[0].convert("RGB") + +output = pipe( + prompt=prompt, + image=image, + control_image=control_image, + mask_image=mask_image, + num_inference_steps=30, + strength=0.9, + guidance_scale=10.0, + generator=torch.Generator().manual_seed(42), +).images[0] +make_image_grid([image, control_image, mask_image, output.resize(image.size)], rows=1, cols=4).save("output.png") +``` + +## FluxControlInpaintPipeline +[[autodoc]] FluxControlInpaintPipeline + - all + - __call__ + + +## FluxPipelineOutput +[[autodoc]] pipelines.flux.pipeline_output.FluxPipelineOutput \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet.md new file mode 100644 index 0000000000000000000000000000000000000000..11f2c4f11f73bacf269967316a14fb34807825dd --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet.md @@ -0,0 +1,82 @@ + + +# ControlNet + +
+ LoRA +
+ +ControlNet was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, and Maneesh Agrawala. + +With a ControlNet model, you can provide an additional control image to condition and control Stable Diffusion generation. For example, if you provide a depth map, the ControlNet model generates an image that'll preserve the spatial information from the depth map. It is a more flexible and accurate way to control the image generation process. + +The abstract from the paper is: + +*We present ControlNet, a neural network architecture to add spatial conditioning controls to large, pretrained text-to-image diffusion models. ControlNet locks the production-ready large diffusion models, and reuses their deep and robust encoding layers pretrained with billions of images as a strong backbone to learn a diverse set of conditional controls. The neural architecture is connected with "zero convolutions" (zero-initialized convolution layers) that progressively grow the parameters from zero and ensure that no harmful noise could affect the finetuning. We test various conditioning controls, eg, edges, depth, segmentation, human pose, etc, with Stable Diffusion, using single or multiple conditions, with or without prompts. We show that the training of ControlNets is robust with small (<50k) and large (>1m) datasets. Extensive results show that ControlNet may facilitate wider applications to control image diffusion models.* + +This model was contributed by [takuma104](https://huggingface.co/takuma104). ❤️ + +The original codebase can be found at [lllyasviel/ControlNet](https://github.com/lllyasviel/ControlNet), and you can find official ControlNet checkpoints on [lllyasviel's](https://huggingface.co/lllyasviel) Hub profile. + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## StableDiffusionControlNetPipeline +[[autodoc]] StableDiffusionControlNetPipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_vae_slicing + - disable_vae_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + - load_textual_inversion + +## StableDiffusionControlNetImg2ImgPipeline +[[autodoc]] StableDiffusionControlNetImg2ImgPipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_vae_slicing + - disable_vae_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + - load_textual_inversion + +## StableDiffusionControlNetInpaintPipeline +[[autodoc]] StableDiffusionControlNetInpaintPipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_vae_slicing + - disable_vae_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + - load_textual_inversion + +## StableDiffusionPipelineOutput +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput + +## FlaxStableDiffusionControlNetPipeline +[[autodoc]] FlaxStableDiffusionControlNetPipeline + - all + - __call__ + +## FlaxStableDiffusionControlNetPipelineOutput +[[autodoc]] pipelines.stable_diffusion.FlaxStableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_flux.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_flux.md new file mode 100644 index 0000000000000000000000000000000000000000..1bb15d7aabb2b1f77857e0e720718d74f9ce0581 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_flux.md @@ -0,0 +1,60 @@ + + +# ControlNet with Flux.1 + +
+ LoRA +
+ +FluxControlNetPipeline is an implementation of ControlNet for Flux.1. + +ControlNet was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, and Maneesh Agrawala. + +With a ControlNet model, you can provide an additional control image to condition and control Stable Diffusion generation. For example, if you provide a depth map, the ControlNet model generates an image that'll preserve the spatial information from the depth map. It is a more flexible and accurate way to control the image generation process. + +The abstract from the paper is: + +*We present ControlNet, a neural network architecture to add spatial conditioning controls to large, pretrained text-to-image diffusion models. ControlNet locks the production-ready large diffusion models, and reuses their deep and robust encoding layers pretrained with billions of images as a strong backbone to learn a diverse set of conditional controls. The neural architecture is connected with "zero convolutions" (zero-initialized convolution layers) that progressively grow the parameters from zero and ensure that no harmful noise could affect the finetuning. We test various conditioning controls, eg, edges, depth, segmentation, human pose, etc, with Stable Diffusion, using single or multiple conditions, with or without prompts. We show that the training of ControlNets is robust with small (<50k) and large (>1m) datasets. Extensive results show that ControlNet may facilitate wider applications to control image diffusion models.* + +This controlnet code is implemented by [The InstantX Team](https://huggingface.co/InstantX). You can find pre-trained checkpoints for Flux-ControlNet in the table below: + + +| ControlNet type | Developer | Link | +| -------- | ---------- | ---- | +| Canny | [The InstantX Team](https://huggingface.co/InstantX) | [Link](https://huggingface.co/InstantX/FLUX.1-dev-Controlnet-Canny) | +| Depth | [The InstantX Team](https://huggingface.co/InstantX) | [Link](https://huggingface.co/Shakker-Labs/FLUX.1-dev-ControlNet-Depth) | +| Union | [The InstantX Team](https://huggingface.co/InstantX) | [Link](https://huggingface.co/InstantX/FLUX.1-dev-Controlnet-Union) | + +XLabs ControlNets are also supported, which was contributed by the [XLabs team](https://huggingface.co/XLabs-AI). + +| ControlNet type | Developer | Link | +| -------- | ---------- | ---- | +| Canny | [The XLabs Team](https://huggingface.co/XLabs-AI) | [Link](https://huggingface.co/XLabs-AI/flux-controlnet-canny-diffusers) | +| Depth | [The XLabs Team](https://huggingface.co/XLabs-AI) | [Link](https://huggingface.co/XLabs-AI/flux-controlnet-depth-diffusers) | +| HED | [The XLabs Team](https://huggingface.co/XLabs-AI) | [Link](https://huggingface.co/XLabs-AI/flux-controlnet-hed-diffusers) | + + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## FluxControlNetPipeline +[[autodoc]] FluxControlNetPipeline + - all + - __call__ + + +## FluxPipelineOutput +[[autodoc]] pipelines.flux.pipeline_output.FluxPipelineOutput \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_hunyuandit.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_hunyuandit.md new file mode 100644 index 0000000000000000000000000000000000000000..c72b493f0e799afc3f728c2bfe5418dbb196102c --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_hunyuandit.md @@ -0,0 +1,36 @@ + + +# ControlNet with Hunyuan-DiT + +HunyuanDiTControlNetPipeline is an implementation of ControlNet for [Hunyuan-DiT](https://huggingface.co/papers/2405.08748). + +ControlNet was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, and Maneesh Agrawala. + +With a ControlNet model, you can provide an additional control image to condition and control Hunyuan-DiT generation. For example, if you provide a depth map, the ControlNet model generates an image that'll preserve the spatial information from the depth map. It is a more flexible and accurate way to control the image generation process. + +The abstract from the paper is: + +*We present ControlNet, a neural network architecture to add spatial conditioning controls to large, pretrained text-to-image diffusion models. ControlNet locks the production-ready large diffusion models, and reuses their deep and robust encoding layers pretrained with billions of images as a strong backbone to learn a diverse set of conditional controls. The neural architecture is connected with "zero convolutions" (zero-initialized convolution layers) that progressively grow the parameters from zero and ensure that no harmful noise could affect the finetuning. We test various conditioning controls, eg, edges, depth, segmentation, human pose, etc, with Stable Diffusion, using single or multiple conditions, with or without prompts. We show that the training of ControlNets is robust with small (<50k) and large (>1m) datasets. Extensive results show that ControlNet may facilitate wider applications to control image diffusion models.* + +This code is implemented by Tencent Hunyuan Team. You can find pre-trained checkpoints for Hunyuan-DiT ControlNets on [Tencent Hunyuan](https://huggingface.co/Tencent-Hunyuan). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## HunyuanDiTControlNetPipeline +[[autodoc]] HunyuanDiTControlNetPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_sana.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_sana.md new file mode 100644 index 0000000000000000000000000000000000000000..fa04591532c98db67680d6ac68330282217661bb --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_sana.md @@ -0,0 +1,36 @@ + + +# ControlNet + +
+ LoRA +
+ +ControlNet was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, and Maneesh Agrawala. + +With a ControlNet model, you can provide an additional control image to condition and control Stable Diffusion generation. For example, if you provide a depth map, the ControlNet model generates an image that'll preserve the spatial information from the depth map. It is a more flexible and accurate way to control the image generation process. + +The abstract from the paper is: + +*We present ControlNet, a neural network architecture to add spatial conditioning controls to large, pretrained text-to-image diffusion models. ControlNet locks the production-ready large diffusion models, and reuses their deep and robust encoding layers pretrained with billions of images as a strong backbone to learn a diverse set of conditional controls. The neural architecture is connected with "zero convolutions" (zero-initialized convolution layers) that progressively grow the parameters from zero and ensure that no harmful noise could affect the finetuning. We test various conditioning controls, eg, edges, depth, segmentation, human pose, etc, with Stable Diffusion, using single or multiple conditions, with or without prompts. We show that the training of ControlNets is robust with small (<50k) and large (>1m) datasets. Extensive results show that ControlNet may facilitate wider applications to control image diffusion models.* + +This pipeline was contributed by [ishan24](https://huggingface.co/ishan24). ❤️ +The original codebase can be found at [NVlabs/Sana](https://github.com/NVlabs/Sana), and you can find official ControlNet checkpoints on [Efficient-Large-Model's](https://huggingface.co/Efficient-Large-Model) Hub profile. + +## SanaControlNetPipeline +[[autodoc]] SanaControlNetPipeline + - all + - __call__ + +## SanaPipelineOutput +[[autodoc]] pipelines.sana.pipeline_output.SanaPipelineOutput \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_sd3.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_sd3.md new file mode 100644 index 0000000000000000000000000000000000000000..cee52ef5d76eef7530221119b1c4c4a48df0f564 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_sd3.md @@ -0,0 +1,58 @@ + + +# ControlNet with Stable Diffusion 3 + +
+ LoRA +
+ +StableDiffusion3ControlNetPipeline is an implementation of ControlNet for Stable Diffusion 3. + +ControlNet was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, and Maneesh Agrawala. + +With a ControlNet model, you can provide an additional control image to condition and control Stable Diffusion generation. For example, if you provide a depth map, the ControlNet model generates an image that'll preserve the spatial information from the depth map. It is a more flexible and accurate way to control the image generation process. + +The abstract from the paper is: + +*We present ControlNet, a neural network architecture to add spatial conditioning controls to large, pretrained text-to-image diffusion models. ControlNet locks the production-ready large diffusion models, and reuses their deep and robust encoding layers pretrained with billions of images as a strong backbone to learn a diverse set of conditional controls. The neural architecture is connected with "zero convolutions" (zero-initialized convolution layers) that progressively grow the parameters from zero and ensure that no harmful noise could affect the finetuning. We test various conditioning controls, eg, edges, depth, segmentation, human pose, etc, with Stable Diffusion, using single or multiple conditions, with or without prompts. We show that the training of ControlNets is robust with small (<50k) and large (>1m) datasets. Extensive results show that ControlNet may facilitate wider applications to control image diffusion models.* + +This controlnet code is mainly implemented by [The InstantX Team](https://huggingface.co/InstantX). The inpainting-related code was developed by [The Alimama Creative Team](https://huggingface.co/alimama-creative). You can find pre-trained checkpoints for SD3-ControlNet in the table below: + + +| ControlNet type | Developer | Link | +| -------- | ---------- | ---- | +| Canny | [The InstantX Team](https://huggingface.co/InstantX) | [Link](https://huggingface.co/InstantX/SD3-Controlnet-Canny) | +| Depth | [The InstantX Team](https://huggingface.co/InstantX) | [Link](https://huggingface.co/InstantX/SD3-Controlnet-Depth) | +| Pose | [The InstantX Team](https://huggingface.co/InstantX) | [Link](https://huggingface.co/InstantX/SD3-Controlnet-Pose) | +| Tile | [The InstantX Team](https://huggingface.co/InstantX) | [Link](https://huggingface.co/InstantX/SD3-Controlnet-Tile) | +| Inpainting | [The AlimamaCreative Team](https://huggingface.co/alimama-creative) | [link](https://huggingface.co/alimama-creative/SD3-Controlnet-Inpainting) | + + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## StableDiffusion3ControlNetPipeline +[[autodoc]] StableDiffusion3ControlNetPipeline + - all + - __call__ + +## StableDiffusion3ControlNetInpaintingPipeline +[[autodoc]] pipelines.controlnet_sd3.pipeline_stable_diffusion_3_controlnet_inpainting.StableDiffusion3ControlNetInpaintingPipeline + - all + - __call__ + +## StableDiffusion3PipelineOutput +[[autodoc]] pipelines.stable_diffusion_3.pipeline_output.StableDiffusion3PipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_sdxl.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_sdxl.md new file mode 100644 index 0000000000000000000000000000000000000000..f299702297b4e48dbda3c1b51983570beabe66d9 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_sdxl.md @@ -0,0 +1,59 @@ + + +# ControlNet with Stable Diffusion XL + +
+ LoRA +
+ +ControlNet was introduced in [Adding Conditional Control to Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.05543) by Lvmin Zhang, Anyi Rao, and Maneesh Agrawala. + +With a ControlNet model, you can provide an additional control image to condition and control Stable Diffusion generation. For example, if you provide a depth map, the ControlNet model generates an image that'll preserve the spatial information from the depth map. It is a more flexible and accurate way to control the image generation process. + +The abstract from the paper is: + +*We present ControlNet, a neural network architecture to add spatial conditioning controls to large, pretrained text-to-image diffusion models. ControlNet locks the production-ready large diffusion models, and reuses their deep and robust encoding layers pretrained with billions of images as a strong backbone to learn a diverse set of conditional controls. The neural architecture is connected with "zero convolutions" (zero-initialized convolution layers) that progressively grow the parameters from zero and ensure that no harmful noise could affect the finetuning. We test various conditioning controls, eg, edges, depth, segmentation, human pose, etc, with Stable Diffusion, using single or multiple conditions, with or without prompts. We show that the training of ControlNets is robust with small (<50k) and large (>1m) datasets. Extensive results show that ControlNet may facilitate wider applications to control image diffusion models.* + +You can find additional smaller Stable Diffusion XL (SDXL) ControlNet checkpoints from the 🤗 [Diffusers](https://huggingface.co/diffusers) Hub organization, and browse [community-trained](https://huggingface.co/models?other=stable-diffusion-xl&other=controlnet) checkpoints on the Hub. + + + +🧪 Many of the SDXL ControlNet checkpoints are experimental, and there is a lot of room for improvement. Feel free to open an [Issue](https://github.com/huggingface/diffusers/issues/new/choose) and leave us feedback on how we can improve! + + + +If you don't see a checkpoint you're interested in, you can train your own SDXL ControlNet with our [training script](../../../../../examples/controlnet/README_sdxl). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## StableDiffusionXLControlNetPipeline +[[autodoc]] StableDiffusionXLControlNetPipeline + - all + - __call__ + +## StableDiffusionXLControlNetImg2ImgPipeline +[[autodoc]] StableDiffusionXLControlNetImg2ImgPipeline + - all + - __call__ + +## StableDiffusionXLControlNetInpaintPipeline +[[autodoc]] StableDiffusionXLControlNetInpaintPipeline + - all + - __call__ + +## StableDiffusionPipelineOutput +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_union.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_union.md new file mode 100644 index 0000000000000000000000000000000000000000..58ae19e778dd7960947965064d4b864c79f3ed8f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnet_union.md @@ -0,0 +1,39 @@ + + +# ControlNetUnion + +
+ LoRA +
+ +ControlNetUnionModel is an implementation of ControlNet for Stable Diffusion XL. + +The ControlNet model was introduced in [ControlNetPlus](https://github.com/xinsir6/ControlNetPlus) by xinsir6. It supports multiple conditioning inputs without increasing computation. + +*We design a new architecture that can support 10+ control types in condition text-to-image generation and can generate high resolution images visually comparable with midjourney. The network is based on the original ControlNet architecture, we propose two new modules to: 1 Extend the original ControlNet to support different image conditions using the same network parameter. 2 Support multiple conditions input without increasing computation offload, which is especially important for designers who want to edit image in detail, different conditions use the same condition encoder, without adding extra computations or parameters.* + + +## StableDiffusionXLControlNetUnionPipeline +[[autodoc]] StableDiffusionXLControlNetUnionPipeline + - all + - __call__ + +## StableDiffusionXLControlNetUnionImg2ImgPipeline +[[autodoc]] StableDiffusionXLControlNetUnionImg2ImgPipeline + - all + - __call__ + +## StableDiffusionXLControlNetUnionInpaintPipeline +[[autodoc]] StableDiffusionXLControlNetUnionInpaintPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnetxs.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnetxs.md new file mode 100644 index 0000000000000000000000000000000000000000..2eebcc6b74d3d5d9e913cf9cd1d4ae89b9f33164 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnetxs.md @@ -0,0 +1,43 @@ + + +# ControlNet-XS + +
+ LoRA +
+ +ControlNet-XS was introduced in [ControlNet-XS](https://vislearn.github.io/ControlNet-XS/) by Denis Zavadski and Carsten Rother. It is based on the observation that the control model in the [original ControlNet](https://huggingface.co/papers/2302.05543) can be made much smaller and still produce good results. + +Like the original ControlNet model, you can provide an additional control image to condition and control Stable Diffusion generation. For example, if you provide a depth map, the ControlNet model generates an image that'll preserve the spatial information from the depth map. It is a more flexible and accurate way to control the image generation process. + +ControlNet-XS generates images with comparable quality to a regular ControlNet, but it is 20-25% faster ([see benchmark](https://github.com/UmerHA/controlnet-xs-benchmark/blob/main/Speed%20Benchmark.ipynb) with StableDiffusion-XL) and uses ~45% less memory. + +Here's the overview from the [project page](https://vislearn.github.io/ControlNet-XS/): + +*With increasing computing capabilities, current model architectures appear to follow the trend of simply upscaling all components without validating the necessity for doing so. In this project we investigate the size and architectural design of ControlNet [Zhang et al., 2023] for controlling the image generation process with stable diffusion-based models. We show that a new architecture with as little as 1% of the parameters of the base model achieves state-of-the art results, considerably better than ControlNet in terms of FID score. Hence we call it ControlNet-XS. We provide the code for controlling StableDiffusion-XL [Podell et al., 2023] (Model B, 48M Parameters) and StableDiffusion 2.1 [Rombach et al. 2022] (Model B, 14M Parameters), all under openrail license.* + +This model was contributed by [UmerHA](https://twitter.com/UmerHAdil). ❤️ + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## StableDiffusionControlNetXSPipeline +[[autodoc]] StableDiffusionControlNetXSPipeline + - all + - __call__ + +## StableDiffusionPipelineOutput +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnetxs_sdxl.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnetxs_sdxl.md new file mode 100644 index 0000000000000000000000000000000000000000..0862a5d79878fff3ece935cf2dd96becd08b869b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/controlnetxs_sdxl.md @@ -0,0 +1,45 @@ + + +# ControlNet-XS with Stable Diffusion XL + +ControlNet-XS was introduced in [ControlNet-XS](https://vislearn.github.io/ControlNet-XS/) by Denis Zavadski and Carsten Rother. It is based on the observation that the control model in the [original ControlNet](https://huggingface.co/papers/2302.05543) can be made much smaller and still produce good results. + +Like the original ControlNet model, you can provide an additional control image to condition and control Stable Diffusion generation. For example, if you provide a depth map, the ControlNet model generates an image that'll preserve the spatial information from the depth map. It is a more flexible and accurate way to control the image generation process. + +ControlNet-XS generates images with comparable quality to a regular ControlNet, but it is 20-25% faster ([see benchmark](https://github.com/UmerHA/controlnet-xs-benchmark/blob/main/Speed%20Benchmark.ipynb)) and uses ~45% less memory. + +Here's the overview from the [project page](https://vislearn.github.io/ControlNet-XS/): + +*With increasing computing capabilities, current model architectures appear to follow the trend of simply upscaling all components without validating the necessity for doing so. In this project we investigate the size and architectural design of ControlNet [Zhang et al., 2023] for controlling the image generation process with stable diffusion-based models. We show that a new architecture with as little as 1% of the parameters of the base model achieves state-of-the art results, considerably better than ControlNet in terms of FID score. Hence we call it ControlNet-XS. We provide the code for controlling StableDiffusion-XL [Podell et al., 2023] (Model B, 48M Parameters) and StableDiffusion 2.1 [Rombach et al. 2022] (Model B, 14M Parameters), all under openrail license.* + +This model was contributed by [UmerHA](https://twitter.com/UmerHAdil). ❤️ + + + +🧪 Many of the SDXL ControlNet checkpoints are experimental, and there is a lot of room for improvement. Feel free to open an [Issue](https://github.com/huggingface/diffusers/issues/new/choose) and leave us feedback on how we can improve! + + + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## StableDiffusionXLControlNetXSPipeline +[[autodoc]] StableDiffusionXLControlNetXSPipeline + - all + - __call__ + +## StableDiffusionPipelineOutput +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/cosmos.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/cosmos.md new file mode 100644 index 0000000000000000000000000000000000000000..c033d6c8210560519968855e41e248a026a73b83 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/cosmos.md @@ -0,0 +1,41 @@ + + +# Cosmos + +[Cosmos World Foundation Model Platform for Physical AI](https://huggingface.co/papers/2501.03575) by NVIDIA. + +*Physical AI needs to be trained digitally first. It needs a digital twin of itself, the policy model, and a digital twin of the world, the world model. In this paper, we present the Cosmos World Foundation Model Platform to help developers build customized world models for their Physical AI setups. We position a world foundation model as a general-purpose world model that can be fine-tuned into customized world models for downstream applications. Our platform covers a video curation pipeline, pre-trained world foundation models, examples of post-training of pre-trained world foundation models, and video tokenizers. To help Physical AI builders solve the most critical problems of our society, we make our platform open-source and our models open-weight with permissive licenses available via https://github.com/NVIDIA/Cosmos.* + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## CosmosTextToWorldPipeline + +[[autodoc]] CosmosTextToWorldPipeline + - all + - __call__ + +## CosmosVideoToWorldPipeline + +[[autodoc]] CosmosVideoToWorldPipeline + - all + - __call__ + +## CosmosPipelineOutput + +[[autodoc]] pipelines.cosmos.pipeline_output.CosmosPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/dance_diffusion.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/dance_diffusion.md new file mode 100644 index 0000000000000000000000000000000000000000..9b6e7b66e1984c3b1e146e6ae8f4f6085793728d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/dance_diffusion.md @@ -0,0 +1,32 @@ + + +# Dance Diffusion + +[Dance Diffusion](https://github.com/Harmonai-org/sample-generator) is by Zach Evans. + +Dance Diffusion is the first in a suite of generative audio tools for producers and musicians released by [Harmonai](https://github.com/Harmonai-org). + + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## DanceDiffusionPipeline +[[autodoc]] DanceDiffusionPipeline + - all + - __call__ + +## AudioPipelineOutput +[[autodoc]] pipelines.AudioPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/ddim.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/ddim.md new file mode 100644 index 0000000000000000000000000000000000000000..6802da739cd5db62ca4cb2ca328937809ff7cba1 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/ddim.md @@ -0,0 +1,29 @@ + + +# DDIM + +[Denoising Diffusion Implicit Models](https://huggingface.co/papers/2010.02502) (DDIM) by Jiaming Song, Chenlin Meng and Stefano Ermon. + +The abstract from the paper is: + +*Denoising diffusion probabilistic models (DDPMs) have achieved high quality image generation without adversarial training, yet they require simulating a Markov chain for many steps to produce a sample. To accelerate sampling, we present denoising diffusion implicit models (DDIMs), a more efficient class of iterative implicit probabilistic models with the same training procedure as DDPMs. In DDPMs, the generative process is defined as the reverse of a Markovian diffusion process. We construct a class of non-Markovian diffusion processes that lead to the same training objective, but whose reverse process can be much faster to sample from. We empirically demonstrate that DDIMs can produce high quality samples 10× to 50× faster in terms of wall-clock time compared to DDPMs, allow us to trade off computation for sample quality, and can perform semantically meaningful image interpolation directly in the latent space.* + +The original codebase can be found at [ermongroup/ddim](https://github.com/ermongroup/ddim). + +## DDIMPipeline +[[autodoc]] DDIMPipeline + - all + - __call__ + +## ImagePipelineOutput +[[autodoc]] pipelines.ImagePipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/ddpm.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/ddpm.md new file mode 100644 index 0000000000000000000000000000000000000000..0935f0bec79c832038ac6581830e5f9c0e783322 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/ddpm.md @@ -0,0 +1,35 @@ + + +# DDPM + +[Denoising Diffusion Probabilistic Models](https://huggingface.co/papers/2006.11239) (DDPM) by Jonathan Ho, Ajay Jain and Pieter Abbeel proposes a diffusion based model of the same name. In the 🤗 Diffusers library, DDPM refers to the *discrete denoising scheduler* from the paper as well as the pipeline. + +The abstract from the paper is: + +*We present high quality image synthesis results using diffusion probabilistic models, a class of latent variable models inspired by considerations from nonequilibrium thermodynamics. Our best results are obtained by training on a weighted variational bound designed according to a novel connection between diffusion probabilistic models and denoising score matching with Langevin dynamics, and our models naturally admit a progressive lossy decompression scheme that can be interpreted as a generalization of autoregressive decoding. On the unconditional CIFAR10 dataset, we obtain an Inception score of 9.46 and a state-of-the-art FID score of 3.17. On 256x256 LSUN, we obtain sample quality similar to ProgressiveGAN.* + +The original codebase can be found at [hohonathanho/diffusion](https://github.com/hojonathanho/diffusion). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +# DDPMPipeline +[[autodoc]] DDPMPipeline + - all + - __call__ + +## ImagePipelineOutput +[[autodoc]] pipelines.ImagePipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/deepfloyd_if.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/deepfloyd_if.md new file mode 100644 index 0000000000000000000000000000000000000000..006422281a1f2b64b39df82520909a6742cd0a3d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/deepfloyd_if.md @@ -0,0 +1,511 @@ + + +# DeepFloyd IF + +
+ LoRA + MPS +
+ +## Overview + +DeepFloyd IF is a novel state-of-the-art open-source text-to-image model with a high degree of photorealism and language understanding. +The model is a modular composed of a frozen text encoder and three cascaded pixel diffusion modules: +- Stage 1: a base model that generates 64x64 px image based on text prompt, +- Stage 2: a 64x64 px => 256x256 px super-resolution model, and +- Stage 3: a 256x256 px => 1024x1024 px super-resolution model +Stage 1 and Stage 2 utilize a frozen text encoder based on the T5 transformer to extract text embeddings, which are then fed into a UNet architecture enhanced with cross-attention and attention pooling. +Stage 3 is [Stability AI's x4 Upscaling model](https://huggingface.co/stabilityai/stable-diffusion-x4-upscaler). +The result is a highly efficient model that outperforms current state-of-the-art models, achieving a zero-shot FID score of 6.66 on the COCO dataset. +Our work underscores the potential of larger UNet architectures in the first stage of cascaded diffusion models and depicts a promising future for text-to-image synthesis. + +## Usage + +Before you can use IF, you need to accept its usage conditions. To do so: +1. Make sure to have a [Hugging Face account](https://huggingface.co/join) and be logged in. +2. Accept the license on the model card of [DeepFloyd/IF-I-XL-v1.0](https://huggingface.co/DeepFloyd/IF-I-XL-v1.0). Accepting the license on the stage I model card will auto accept for the other IF models. +3. Make sure to login locally. Install `huggingface_hub`: +```sh +pip install huggingface_hub --upgrade +``` + +run the login function in a Python shell: + +```py +from huggingface_hub import login + +login() +``` + +and enter your [Hugging Face Hub access token](https://huggingface.co/docs/hub/security-tokens#what-are-user-access-tokens). + +Next we install `diffusers` and dependencies: + +```sh +pip install -q diffusers accelerate transformers +``` + +The following sections give more in-detail examples of how to use IF. Specifically: + +- [Text-to-Image Generation](#text-to-image-generation) +- [Image-to-Image Generation](#text-guided-image-to-image-generation) +- [Inpainting](#text-guided-inpainting-generation) +- [Reusing model weights](#converting-between-different-pipelines) +- [Speed optimization](#optimizing-for-speed) +- [Memory optimization](#optimizing-for-memory) + +**Available checkpoints** +- *Stage-1* + - [DeepFloyd/IF-I-XL-v1.0](https://huggingface.co/DeepFloyd/IF-I-XL-v1.0) + - [DeepFloyd/IF-I-L-v1.0](https://huggingface.co/DeepFloyd/IF-I-L-v1.0) + - [DeepFloyd/IF-I-M-v1.0](https://huggingface.co/DeepFloyd/IF-I-M-v1.0) + +- *Stage-2* + - [DeepFloyd/IF-II-L-v1.0](https://huggingface.co/DeepFloyd/IF-II-L-v1.0) + - [DeepFloyd/IF-II-M-v1.0](https://huggingface.co/DeepFloyd/IF-II-M-v1.0) + +- *Stage-3* + - [stabilityai/stable-diffusion-x4-upscaler](https://huggingface.co/stabilityai/stable-diffusion-x4-upscaler) + + +**Google Colab** +[![Open In Colab](https://colab.research.google.com/assets/colab-badge.svg)](https://colab.research.google.com/github/huggingface/notebooks/blob/main/diffusers/deepfloyd_if_free_tier_google_colab.ipynb) + +### Text-to-Image Generation + +By default diffusers makes use of [model cpu offloading](../../optimization/memory#model-offloading) to run the whole IF pipeline with as little as 14 GB of VRAM. + +```python +from diffusers import DiffusionPipeline +from diffusers.utils import pt_to_pil, make_image_grid +import torch + +# stage 1 +stage_1 = DiffusionPipeline.from_pretrained("DeepFloyd/IF-I-XL-v1.0", variant="fp16", torch_dtype=torch.float16) +stage_1.enable_model_cpu_offload() + +# stage 2 +stage_2 = DiffusionPipeline.from_pretrained( + "DeepFloyd/IF-II-L-v1.0", text_encoder=None, variant="fp16", torch_dtype=torch.float16 +) +stage_2.enable_model_cpu_offload() + +# stage 3 +safety_modules = { + "feature_extractor": stage_1.feature_extractor, + "safety_checker": stage_1.safety_checker, + "watermarker": stage_1.watermarker, +} +stage_3 = DiffusionPipeline.from_pretrained( + "stabilityai/stable-diffusion-x4-upscaler", **safety_modules, torch_dtype=torch.float16 +) +stage_3.enable_model_cpu_offload() + +prompt = 'a photo of a kangaroo wearing an orange hoodie and blue sunglasses standing in front of the eiffel tower holding a sign that says "very deep learning"' +generator = torch.manual_seed(1) + +# text embeds +prompt_embeds, negative_embeds = stage_1.encode_prompt(prompt) + +# stage 1 +stage_1_output = stage_1( + prompt_embeds=prompt_embeds, negative_prompt_embeds=negative_embeds, generator=generator, output_type="pt" +).images +#pt_to_pil(stage_1_output)[0].save("./if_stage_I.png") + +# stage 2 +stage_2_output = stage_2( + image=stage_1_output, + prompt_embeds=prompt_embeds, + negative_prompt_embeds=negative_embeds, + generator=generator, + output_type="pt", +).images +#pt_to_pil(stage_2_output)[0].save("./if_stage_II.png") + +# stage 3 +stage_3_output = stage_3(prompt=prompt, image=stage_2_output, noise_level=100, generator=generator).images +#stage_3_output[0].save("./if_stage_III.png") +make_image_grid([pt_to_pil(stage_1_output)[0], pt_to_pil(stage_2_output)[0], stage_3_output[0]], rows=1, rows=3) +``` + +### Text Guided Image-to-Image Generation + +The same IF model weights can be used for text-guided image-to-image translation or image variation. +In this case just make sure to load the weights using the [`IFImg2ImgPipeline`] and [`IFImg2ImgSuperResolutionPipeline`] pipelines. + +**Note**: You can also directly move the weights of the text-to-image pipelines to the image-to-image pipelines +without loading them twice by making use of the [`~DiffusionPipeline.components`] argument as explained [here](#converting-between-different-pipelines). + +```python +from diffusers import IFImg2ImgPipeline, IFImg2ImgSuperResolutionPipeline, DiffusionPipeline +from diffusers.utils import pt_to_pil, load_image, make_image_grid +import torch + +# download image +url = "https://raw.githubusercontent.com/CompVis/stable-diffusion/main/assets/stable-samples/img2img/sketch-mountains-input.jpg" +original_image = load_image(url) +original_image = original_image.resize((768, 512)) + +# stage 1 +stage_1 = IFImg2ImgPipeline.from_pretrained("DeepFloyd/IF-I-XL-v1.0", variant="fp16", torch_dtype=torch.float16) +stage_1.enable_model_cpu_offload() + +# stage 2 +stage_2 = IFImg2ImgSuperResolutionPipeline.from_pretrained( + "DeepFloyd/IF-II-L-v1.0", text_encoder=None, variant="fp16", torch_dtype=torch.float16 +) +stage_2.enable_model_cpu_offload() + +# stage 3 +safety_modules = { + "feature_extractor": stage_1.feature_extractor, + "safety_checker": stage_1.safety_checker, + "watermarker": stage_1.watermarker, +} +stage_3 = DiffusionPipeline.from_pretrained( + "stabilityai/stable-diffusion-x4-upscaler", **safety_modules, torch_dtype=torch.float16 +) +stage_3.enable_model_cpu_offload() + +prompt = "A fantasy landscape in style minecraft" +generator = torch.manual_seed(1) + +# text embeds +prompt_embeds, negative_embeds = stage_1.encode_prompt(prompt) + +# stage 1 +stage_1_output = stage_1( + image=original_image, + prompt_embeds=prompt_embeds, + negative_prompt_embeds=negative_embeds, + generator=generator, + output_type="pt", +).images +#pt_to_pil(stage_1_output)[0].save("./if_stage_I.png") + +# stage 2 +stage_2_output = stage_2( + image=stage_1_output, + original_image=original_image, + prompt_embeds=prompt_embeds, + negative_prompt_embeds=negative_embeds, + generator=generator, + output_type="pt", +).images +#pt_to_pil(stage_2_output)[0].save("./if_stage_II.png") + +# stage 3 +stage_3_output = stage_3(prompt=prompt, image=stage_2_output, generator=generator, noise_level=100).images +#stage_3_output[0].save("./if_stage_III.png") +make_image_grid([original_image, pt_to_pil(stage_1_output)[0], pt_to_pil(stage_2_output)[0], stage_3_output[0]], rows=1, rows=4) +``` + +### Text Guided Inpainting Generation + +The same IF model weights can be used for text-guided image-to-image translation or image variation. +In this case just make sure to load the weights using the [`IFInpaintingPipeline`] and [`IFInpaintingSuperResolutionPipeline`] pipelines. + +**Note**: You can also directly move the weights of the text-to-image pipelines to the image-to-image pipelines +without loading them twice by making use of the [`~DiffusionPipeline.components()`] function as explained [here](#converting-between-different-pipelines). + +```python +from diffusers import IFInpaintingPipeline, IFInpaintingSuperResolutionPipeline, DiffusionPipeline +from diffusers.utils import pt_to_pil, load_image, make_image_grid +import torch + +# download image +url = "https://huggingface.co/datasets/diffusers/docs-images/resolve/main/if/person.png" +original_image = load_image(url) + +# download mask +url = "https://huggingface.co/datasets/diffusers/docs-images/resolve/main/if/glasses_mask.png" +mask_image = load_image(url) + +# stage 1 +stage_1 = IFInpaintingPipeline.from_pretrained("DeepFloyd/IF-I-XL-v1.0", variant="fp16", torch_dtype=torch.float16) +stage_1.enable_model_cpu_offload() + +# stage 2 +stage_2 = IFInpaintingSuperResolutionPipeline.from_pretrained( + "DeepFloyd/IF-II-L-v1.0", text_encoder=None, variant="fp16", torch_dtype=torch.float16 +) +stage_2.enable_model_cpu_offload() + +# stage 3 +safety_modules = { + "feature_extractor": stage_1.feature_extractor, + "safety_checker": stage_1.safety_checker, + "watermarker": stage_1.watermarker, +} +stage_3 = DiffusionPipeline.from_pretrained( + "stabilityai/stable-diffusion-x4-upscaler", **safety_modules, torch_dtype=torch.float16 +) +stage_3.enable_model_cpu_offload() + +prompt = "blue sunglasses" +generator = torch.manual_seed(1) + +# text embeds +prompt_embeds, negative_embeds = stage_1.encode_prompt(prompt) + +# stage 1 +stage_1_output = stage_1( + image=original_image, + mask_image=mask_image, + prompt_embeds=prompt_embeds, + negative_prompt_embeds=negative_embeds, + generator=generator, + output_type="pt", +).images +#pt_to_pil(stage_1_output)[0].save("./if_stage_I.png") + +# stage 2 +stage_2_output = stage_2( + image=stage_1_output, + original_image=original_image, + mask_image=mask_image, + prompt_embeds=prompt_embeds, + negative_prompt_embeds=negative_embeds, + generator=generator, + output_type="pt", +).images +#pt_to_pil(stage_1_output)[0].save("./if_stage_II.png") + +# stage 3 +stage_3_output = stage_3(prompt=prompt, image=stage_2_output, generator=generator, noise_level=100).images +#stage_3_output[0].save("./if_stage_III.png") +make_image_grid([original_image, mask_image, pt_to_pil(stage_1_output)[0], pt_to_pil(stage_2_output)[0], stage_3_output[0]], rows=1, rows=5) +``` + +### Converting between different pipelines + +In addition to being loaded with `from_pretrained`, Pipelines can also be loaded directly from each other. + +```python +from diffusers import IFPipeline, IFSuperResolutionPipeline + +pipe_1 = IFPipeline.from_pretrained("DeepFloyd/IF-I-XL-v1.0") +pipe_2 = IFSuperResolutionPipeline.from_pretrained("DeepFloyd/IF-II-L-v1.0") + + +from diffusers import IFImg2ImgPipeline, IFImg2ImgSuperResolutionPipeline + +pipe_1 = IFImg2ImgPipeline(**pipe_1.components) +pipe_2 = IFImg2ImgSuperResolutionPipeline(**pipe_2.components) + + +from diffusers import IFInpaintingPipeline, IFInpaintingSuperResolutionPipeline + +pipe_1 = IFInpaintingPipeline(**pipe_1.components) +pipe_2 = IFInpaintingSuperResolutionPipeline(**pipe_2.components) +``` + +### Optimizing for speed + +The simplest optimization to run IF faster is to move all model components to the GPU. + +```py +pipe = DiffusionPipeline.from_pretrained("DeepFloyd/IF-I-XL-v1.0", variant="fp16", torch_dtype=torch.float16) +pipe.to("cuda") +``` + +You can also run the diffusion process for a shorter number of timesteps. + +This can either be done with the `num_inference_steps` argument: + +```py +pipe("", num_inference_steps=30) +``` + +Or with the `timesteps` argument: + +```py +from diffusers.pipelines.deepfloyd_if import fast27_timesteps + +pipe("", timesteps=fast27_timesteps) +``` + +When doing image variation or inpainting, you can also decrease the number of timesteps +with the strength argument. The strength argument is the amount of noise to add to the input image which also determines how many steps to run in the denoising process. +A smaller number will vary the image less but run faster. + +```py +pipe = IFImg2ImgPipeline.from_pretrained("DeepFloyd/IF-I-XL-v1.0", variant="fp16", torch_dtype=torch.float16) +pipe.to("cuda") + +image = pipe(image=image, prompt="", strength=0.3).images +``` + +You can also use [`torch.compile`](../../optimization/torch2.0). Note that we have not exhaustively tested `torch.compile` +with IF and it might not give expected results. + +```py +from diffusers import DiffusionPipeline +import torch + +pipe = DiffusionPipeline.from_pretrained("DeepFloyd/IF-I-XL-v1.0", variant="fp16", torch_dtype=torch.float16) +pipe.to("cuda") + +pipe.text_encoder = torch.compile(pipe.text_encoder, mode="reduce-overhead", fullgraph=True) +pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True) +``` + +### Optimizing for memory + +When optimizing for GPU memory, we can use the standard diffusers CPU offloading APIs. + +Either the model based CPU offloading, + +```py +pipe = DiffusionPipeline.from_pretrained("DeepFloyd/IF-I-XL-v1.0", variant="fp16", torch_dtype=torch.float16) +pipe.enable_model_cpu_offload() +``` + +or the more aggressive layer based CPU offloading. + +```py +pipe = DiffusionPipeline.from_pretrained("DeepFloyd/IF-I-XL-v1.0", variant="fp16", torch_dtype=torch.float16) +pipe.enable_sequential_cpu_offload() +``` + +Additionally, T5 can be loaded in 8bit precision + +```py +from transformers import T5EncoderModel + +text_encoder = T5EncoderModel.from_pretrained( + "DeepFloyd/IF-I-XL-v1.0", subfolder="text_encoder", device_map="auto", load_in_8bit=True, variant="8bit" +) + +from diffusers import DiffusionPipeline + +pipe = DiffusionPipeline.from_pretrained( + "DeepFloyd/IF-I-XL-v1.0", + text_encoder=text_encoder, # pass the previously instantiated 8bit text encoder + unet=None, + device_map="auto", +) + +prompt_embeds, negative_embeds = pipe.encode_prompt("") +``` + +For CPU RAM constrained machines like Google Colab free tier where we can't load all model components to the CPU at once, we can manually only load the pipeline with +the text encoder or UNet when the respective model components are needed. + +```py +from diffusers import IFPipeline, IFSuperResolutionPipeline +import torch +import gc +from transformers import T5EncoderModel +from diffusers.utils import pt_to_pil, make_image_grid + +text_encoder = T5EncoderModel.from_pretrained( + "DeepFloyd/IF-I-XL-v1.0", subfolder="text_encoder", device_map="auto", load_in_8bit=True, variant="8bit" +) + +# text to image +pipe = DiffusionPipeline.from_pretrained( + "DeepFloyd/IF-I-XL-v1.0", + text_encoder=text_encoder, # pass the previously instantiated 8bit text encoder + unet=None, + device_map="auto", +) + +prompt = 'a photo of a kangaroo wearing an orange hoodie and blue sunglasses standing in front of the eiffel tower holding a sign that says "very deep learning"' +prompt_embeds, negative_embeds = pipe.encode_prompt(prompt) + +# Remove the pipeline so we can re-load the pipeline with the unet +del text_encoder +del pipe +gc.collect() +torch.cuda.empty_cache() + +pipe = IFPipeline.from_pretrained( + "DeepFloyd/IF-I-XL-v1.0", text_encoder=None, variant="fp16", torch_dtype=torch.float16, device_map="auto" +) + +generator = torch.Generator().manual_seed(0) +stage_1_output = pipe( + prompt_embeds=prompt_embeds, + negative_prompt_embeds=negative_embeds, + output_type="pt", + generator=generator, +).images + +#pt_to_pil(stage_1_output)[0].save("./if_stage_I.png") + +# Remove the pipeline so we can load the super-resolution pipeline +del pipe +gc.collect() +torch.cuda.empty_cache() + +# First super resolution + +pipe = IFSuperResolutionPipeline.from_pretrained( + "DeepFloyd/IF-II-L-v1.0", text_encoder=None, variant="fp16", torch_dtype=torch.float16, device_map="auto" +) + +generator = torch.Generator().manual_seed(0) +stage_2_output = pipe( + image=stage_1_output, + prompt_embeds=prompt_embeds, + negative_prompt_embeds=negative_embeds, + output_type="pt", + generator=generator, +).images + +#pt_to_pil(stage_2_output)[0].save("./if_stage_II.png") +make_image_grid([pt_to_pil(stage_1_output)[0], pt_to_pil(stage_2_output)[0]], rows=1, rows=2) +``` + +## Available Pipelines: + +| Pipeline | Tasks | Colab +|---|---|:---:| +| [pipeline_if.py](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/deepfloyd_if/pipeline_if.py) | *Text-to-Image Generation* | - | +| [pipeline_if_superresolution.py](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/deepfloyd_if/pipeline_if_superresolution.py) | *Text-to-Image Generation* | - | +| [pipeline_if_img2img.py](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/deepfloyd_if/pipeline_if_img2img.py) | *Image-to-Image Generation* | - | +| [pipeline_if_img2img_superresolution.py](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/deepfloyd_if/pipeline_if_img2img_superresolution.py) | *Image-to-Image Generation* | - | +| [pipeline_if_inpainting.py](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/deepfloyd_if/pipeline_if_inpainting.py) | *Image-to-Image Generation* | - | +| [pipeline_if_inpainting_superresolution.py](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/deepfloyd_if/pipeline_if_inpainting_superresolution.py) | *Image-to-Image Generation* | - | + +## IFPipeline +[[autodoc]] IFPipeline + - all + - __call__ + +## IFSuperResolutionPipeline +[[autodoc]] IFSuperResolutionPipeline + - all + - __call__ + +## IFImg2ImgPipeline +[[autodoc]] IFImg2ImgPipeline + - all + - __call__ + +## IFImg2ImgSuperResolutionPipeline +[[autodoc]] IFImg2ImgSuperResolutionPipeline + - all + - __call__ + +## IFInpaintingPipeline +[[autodoc]] IFInpaintingPipeline + - all + - __call__ + +## IFInpaintingSuperResolutionPipeline +[[autodoc]] IFInpaintingSuperResolutionPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/diffedit.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/diffedit.md new file mode 100644 index 0000000000000000000000000000000000000000..97cbdcb0c066320283eb68a849eced9940253c58 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/diffedit.md @@ -0,0 +1,55 @@ + + +# DiffEdit + +[DiffEdit: Diffusion-based semantic image editing with mask guidance](https://huggingface.co/papers/2210.11427) is by Guillaume Couairon, Jakob Verbeek, Holger Schwenk, and Matthieu Cord. + +The abstract from the paper is: + +*Image generation has recently seen tremendous advances, with diffusion models allowing to synthesize convincing images for a large variety of text prompts. In this article, we propose DiffEdit, a method to take advantage of text-conditioned diffusion models for the task of semantic image editing, where the goal is to edit an image based on a text query. Semantic image editing is an extension of image generation, with the additional constraint that the generated image should be as similar as possible to a given input image. Current editing methods based on diffusion models usually require to provide a mask, making the task much easier by treating it as a conditional inpainting task. In contrast, our main contribution is able to automatically generate a mask highlighting regions of the input image that need to be edited, by contrasting predictions of a diffusion model conditioned on different text prompts. Moreover, we rely on latent inference to preserve content in those regions of interest and show excellent synergies with mask-based diffusion. DiffEdit achieves state-of-the-art editing performance on ImageNet. In addition, we evaluate semantic image editing in more challenging settings, using images from the COCO dataset as well as text-based generated images.* + +The original codebase can be found at [Xiang-cd/DiffEdit-stable-diffusion](https://github.com/Xiang-cd/DiffEdit-stable-diffusion), and you can try it out in this [demo](https://blog.problemsolversguild.com/technical/research/2022/11/02/DiffEdit-Implementation.html). + +This pipeline was contributed by [clarencechen](https://github.com/clarencechen). ❤️ + +## Tips + +* The pipeline can generate masks that can be fed into other inpainting pipelines. +* In order to generate an image using this pipeline, both an image mask (source and target prompts can be manually specified or generated, and passed to [`~StableDiffusionDiffEditPipeline.generate_mask`]) +and a set of partially inverted latents (generated using [`~StableDiffusionDiffEditPipeline.invert`]) _must_ be provided as arguments when calling the pipeline to generate the final edited image. +* The function [`~StableDiffusionDiffEditPipeline.generate_mask`] exposes two prompt arguments, `source_prompt` and `target_prompt` +that let you control the locations of the semantic edits in the final image to be generated. Let's say, +you wanted to translate from "cat" to "dog". In this case, the edit direction will be "cat -> dog". To reflect +this in the generated mask, you simply have to set the embeddings related to the phrases including "cat" to +`source_prompt` and "dog" to `target_prompt`. +* When generating partially inverted latents using `invert`, assign a caption or text embedding describing the +overall image to the `prompt` argument to help guide the inverse latent sampling process. In most cases, the +source concept is sufficiently descriptive to yield good results, but feel free to explore alternatives. +* When calling the pipeline to generate the final edited image, assign the source concept to `negative_prompt` +and the target concept to `prompt`. Taking the above example, you simply have to set the embeddings related to +the phrases including "cat" to `negative_prompt` and "dog" to `prompt`. +* If you wanted to reverse the direction in the example above, i.e., "dog -> cat", then it's recommended to: + * Swap the `source_prompt` and `target_prompt` in the arguments to `generate_mask`. + * Change the input prompt in [`~StableDiffusionDiffEditPipeline.invert`] to include "dog". + * Swap the `prompt` and `negative_prompt` in the arguments to call the pipeline to generate the final edited image. +* The source and target prompts, or their corresponding embeddings, can also be automatically generated. Please refer to the [DiffEdit](../../using-diffusers/diffedit) guide for more details. + +## StableDiffusionDiffEditPipeline +[[autodoc]] StableDiffusionDiffEditPipeline + - all + - generate_mask + - invert + - __call__ + +## StableDiffusionPipelineOutput +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/dit.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/dit.md new file mode 100644 index 0000000000000000000000000000000000000000..2ee45b631c77e5a033a3d05ed5896a59cec98ea9 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/dit.md @@ -0,0 +1,35 @@ + + +# DiT + +[Scalable Diffusion Models with Transformers](https://huggingface.co/papers/2212.09748) (DiT) is by William Peebles and Saining Xie. + +The abstract from the paper is: + +*We explore a new class of diffusion models based on the transformer architecture. We train latent diffusion models of images, replacing the commonly-used U-Net backbone with a transformer that operates on latent patches. We analyze the scalability of our Diffusion Transformers (DiTs) through the lens of forward pass complexity as measured by Gflops. We find that DiTs with higher Gflops -- through increased transformer depth/width or increased number of input tokens -- consistently have lower FID. In addition to possessing good scalability properties, our largest DiT-XL/2 models outperform all prior diffusion models on the class-conditional ImageNet 512x512 and 256x256 benchmarks, achieving a state-of-the-art FID of 2.27 on the latter.* + +The original codebase can be found at [facebookresearch/dit](https://github.com/facebookresearch/dit). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## DiTPipeline +[[autodoc]] DiTPipeline + - all + - __call__ + +## ImagePipelineOutput +[[autodoc]] pipelines.ImagePipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/easyanimate.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/easyanimate.md new file mode 100644 index 0000000000000000000000000000000000000000..15d44a12b1b6d5e2d886bcda188d06d8f44dfbfe --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/easyanimate.md @@ -0,0 +1,88 @@ + + +# EasyAnimate +[EasyAnimate](https://github.com/aigc-apps/EasyAnimate) by Alibaba PAI. + +The description from it's GitHub page: +*EasyAnimate is a pipeline based on the transformer architecture, designed for generating AI images and videos, and for training baseline models and Lora models for Diffusion Transformer. We support direct prediction from pre-trained EasyAnimate models, allowing for the generation of videos with various resolutions, approximately 6 seconds in length, at 8fps (EasyAnimateV5.1, 1 to 49 frames). Additionally, users can train their own baseline and Lora models for specific style transformations.* + +This pipeline was contributed by [bubbliiiing](https://github.com/bubbliiiing). The original codebase can be found [here](https://huggingface.co/alibaba-pai). The original weights can be found under [hf.co/alibaba-pai](https://huggingface.co/alibaba-pai). + +There are two official EasyAnimate checkpoints for text-to-video and video-to-video. + +| checkpoints | recommended inference dtype | +|:---:|:---:| +| [`alibaba-pai/EasyAnimateV5.1-12b-zh`](https://huggingface.co/alibaba-pai/EasyAnimateV5.1-12b-zh) | torch.float16 | +| [`alibaba-pai/EasyAnimateV5.1-12b-zh-InP`](https://huggingface.co/alibaba-pai/EasyAnimateV5.1-12b-zh-InP) | torch.float16 | + +There is one official EasyAnimate checkpoints available for image-to-video and video-to-video. + +| checkpoints | recommended inference dtype | +|:---:|:---:| +| [`alibaba-pai/EasyAnimateV5.1-12b-zh-InP`](https://huggingface.co/alibaba-pai/EasyAnimateV5.1-12b-zh-InP) | torch.float16 | + +There are two official EasyAnimate checkpoints available for control-to-video. + +| checkpoints | recommended inference dtype | +|:---:|:---:| +| [`alibaba-pai/EasyAnimateV5.1-12b-zh-Control`](https://huggingface.co/alibaba-pai/EasyAnimateV5.1-12b-zh-Control) | torch.float16 | +| [`alibaba-pai/EasyAnimateV5.1-12b-zh-Control-Camera`](https://huggingface.co/alibaba-pai/EasyAnimateV5.1-12b-zh-Control-Camera) | torch.float16 | + +For the EasyAnimateV5.1 series: +- Text-to-video (T2V) and Image-to-video (I2V) works for multiple resolutions. The width and height can vary from 256 to 1024. +- Both T2V and I2V models support generation with 1~49 frames and work best at this value. Exporting videos at 8 FPS is recommended. + +## Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`EasyAnimatePipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, EasyAnimateTransformer3DModel, EasyAnimatePipeline +from diffusers.utils import export_to_video + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = EasyAnimateTransformer3DModel.from_pretrained( + "alibaba-pai/EasyAnimateV5.1-12b-zh", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +pipeline = EasyAnimatePipeline.from_pretrained( + "alibaba-pai/EasyAnimateV5.1-12b-zh", + transformer=transformer_8bit, + torch_dtype=torch.float16, + device_map="balanced", +) + +prompt = "A cat walks on the grass, realistic style." +negative_prompt = "bad detailed" +video = pipeline(prompt=prompt, negative_prompt=negative_prompt, num_frames=49, num_inference_steps=30).frames[0] +export_to_video(video, "cat.mp4", fps=8) +``` + +## EasyAnimatePipeline + +[[autodoc]] EasyAnimatePipeline + - all + - __call__ + +## EasyAnimatePipelineOutput + +[[autodoc]] pipelines.easyanimate.pipeline_output.EasyAnimatePipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/flux.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/flux.md new file mode 100644 index 0000000000000000000000000000000000000000..0dc8e63364988b42746a879bb13c0670f753ee2c --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/flux.md @@ -0,0 +1,605 @@ + + +# Flux + +
+ LoRA + MPS +
+ +Flux is a series of text-to-image generation models based on diffusion transformers. To know more about Flux, check out the original [blog post](https://blackforestlabs.ai/announcing-black-forest-labs/) by the creators of Flux, Black Forest Labs. + +Original model checkpoints for Flux can be found [here](https://huggingface.co/black-forest-labs). Original inference code can be found [here](https://github.com/black-forest-labs/flux). + + + +Flux can be quite expensive to run on consumer hardware devices. However, you can perform a suite of optimizations to run it faster and in a more memory-friendly manner. Check out [this section](https://huggingface.co/blog/sd3#memory-optimizations-for-sd3) for more details. Additionally, Flux can benefit from quantization for memory efficiency with a trade-off in inference latency. Refer to [this blog post](https://huggingface.co/blog/quanto-diffusers) to learn more. For an exhaustive list of resources, check out [this gist](https://gist.github.com/sayakpaul/b664605caf0aa3bf8585ab109dd5ac9c). + + + +Flux comes in the following variants: + +| model type | model id | +|:----------:|:--------:| +| Timestep-distilled | [`black-forest-labs/FLUX.1-schnell`](https://huggingface.co/black-forest-labs/FLUX.1-schnell) | +| Guidance-distilled | [`black-forest-labs/FLUX.1-dev`](https://huggingface.co/black-forest-labs/FLUX.1-dev) | +| Fill Inpainting/Outpainting (Guidance-distilled) | [`black-forest-labs/FLUX.1-Fill-dev`](https://huggingface.co/black-forest-labs/FLUX.1-Fill-dev) | +| Canny Control (Guidance-distilled) | [`black-forest-labs/FLUX.1-Canny-dev`](https://huggingface.co/black-forest-labs/FLUX.1-Canny-dev) | +| Depth Control (Guidance-distilled) | [`black-forest-labs/FLUX.1-Depth-dev`](https://huggingface.co/black-forest-labs/FLUX.1-Depth-dev) | +| Canny Control (LoRA) | [`black-forest-labs/FLUX.1-Canny-dev-lora`](https://huggingface.co/black-forest-labs/FLUX.1-Canny-dev-lora) | +| Depth Control (LoRA) | [`black-forest-labs/FLUX.1-Depth-dev-lora`](https://huggingface.co/black-forest-labs/FLUX.1-Depth-dev-lora) | +| Redux (Adapter) | [`black-forest-labs/FLUX.1-Redux-dev`](https://huggingface.co/black-forest-labs/FLUX.1-Redux-dev) | + +All checkpoints have different usage which we detail below. + +### Timestep-distilled + +* `max_sequence_length` cannot be more than 256. +* `guidance_scale` needs to be 0. +* As this is a timestep-distilled model, it benefits from fewer sampling steps. + +```python +import torch +from diffusers import FluxPipeline + +pipe = FluxPipeline.from_pretrained("black-forest-labs/FLUX.1-schnell", torch_dtype=torch.bfloat16) +pipe.enable_model_cpu_offload() + +prompt = "A cat holding a sign that says hello world" +out = pipe( + prompt=prompt, + guidance_scale=0., + height=768, + width=1360, + num_inference_steps=4, + max_sequence_length=256, +).images[0] +out.save("image.png") +``` + +### Guidance-distilled + +* The guidance-distilled variant takes about 50 sampling steps for good-quality generation. +* It doesn't have any limitations around the `max_sequence_length`. + +```python +import torch +from diffusers import FluxPipeline + +pipe = FluxPipeline.from_pretrained("black-forest-labs/FLUX.1-dev", torch_dtype=torch.bfloat16) +pipe.enable_model_cpu_offload() + +prompt = "a tiny astronaut hatching from an egg on the moon" +out = pipe( + prompt=prompt, + guidance_scale=3.5, + height=768, + width=1360, + num_inference_steps=50, +).images[0] +out.save("image.png") +``` + +### Fill Inpainting/Outpainting + +* Flux Fill pipeline does not require `strength` as an input like regular inpainting pipelines. +* It supports both inpainting and outpainting. + +```python +import torch +from diffusers import FluxFillPipeline +from diffusers.utils import load_image + +image = load_image("https://huggingface.co/datasets/YiYiXu/testing-images/resolve/main/cup.png") +mask = load_image("https://huggingface.co/datasets/YiYiXu/testing-images/resolve/main/cup_mask.png") + +repo_id = "black-forest-labs/FLUX.1-Fill-dev" +pipe = FluxFillPipeline.from_pretrained(repo_id, torch_dtype=torch.bfloat16).to("cuda") + +image = pipe( + prompt="a white paper cup", + image=image, + mask_image=mask, + height=1632, + width=1232, + max_sequence_length=512, + generator=torch.Generator("cpu").manual_seed(0) +).images[0] +image.save(f"output.png") +``` + +### Canny Control + +**Note:** `black-forest-labs/Flux.1-Canny-dev` is _not_ a [`ControlNetModel`] model. ControlNet models are a separate component from the UNet/Transformer whose residuals are added to the actual underlying model. Canny Control is an alternate architecture that achieves effectively the same results as a ControlNet model would, by using channel-wise concatenation with input control condition and ensuring the transformer learns structure control by following the condition as closely as possible. + +```python +# !pip install -U controlnet-aux +import torch +from controlnet_aux import CannyDetector +from diffusers import FluxControlPipeline +from diffusers.utils import load_image + +pipe = FluxControlPipeline.from_pretrained("black-forest-labs/FLUX.1-Canny-dev", torch_dtype=torch.bfloat16).to("cuda") + +prompt = "A robot made of exotic candies and chocolates of different kinds. The background is filled with confetti and celebratory gifts." +control_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/robot.png") + +processor = CannyDetector() +control_image = processor(control_image, low_threshold=50, high_threshold=200, detect_resolution=1024, image_resolution=1024) + +image = pipe( + prompt=prompt, + control_image=control_image, + height=1024, + width=1024, + num_inference_steps=50, + guidance_scale=30.0, +).images[0] +image.save("output.png") +``` + +Canny Control is also possible with a LoRA variant of this condition. The usage is as follows: + +```python +# !pip install -U controlnet-aux +import torch +from controlnet_aux import CannyDetector +from diffusers import FluxControlPipeline +from diffusers.utils import load_image + +pipe = FluxControlPipeline.from_pretrained("black-forest-labs/FLUX.1-dev", torch_dtype=torch.bfloat16).to("cuda") +pipe.load_lora_weights("black-forest-labs/FLUX.1-Canny-dev-lora") + +prompt = "A robot made of exotic candies and chocolates of different kinds. The background is filled with confetti and celebratory gifts." +control_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/robot.png") + +processor = CannyDetector() +control_image = processor(control_image, low_threshold=50, high_threshold=200, detect_resolution=1024, image_resolution=1024) + +image = pipe( + prompt=prompt, + control_image=control_image, + height=1024, + width=1024, + num_inference_steps=50, + guidance_scale=30.0, +).images[0] +image.save("output.png") +``` + +### Depth Control + +**Note:** `black-forest-labs/Flux.1-Depth-dev` is _not_ a ControlNet model. [`ControlNetModel`] models are a separate component from the UNet/Transformer whose residuals are added to the actual underlying model. Depth Control is an alternate architecture that achieves effectively the same results as a ControlNet model would, by using channel-wise concatenation with input control condition and ensuring the transformer learns structure control by following the condition as closely as possible. + +```python +# !pip install git+https://github.com/huggingface/image_gen_aux +import torch +from diffusers import FluxControlPipeline, FluxTransformer2DModel +from diffusers.utils import load_image +from image_gen_aux import DepthPreprocessor + +pipe = FluxControlPipeline.from_pretrained("black-forest-labs/FLUX.1-Depth-dev", torch_dtype=torch.bfloat16).to("cuda") + +prompt = "A robot made of exotic candies and chocolates of different kinds. The background is filled with confetti and celebratory gifts." +control_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/robot.png") + +processor = DepthPreprocessor.from_pretrained("LiheYoung/depth-anything-large-hf") +control_image = processor(control_image)[0].convert("RGB") + +image = pipe( + prompt=prompt, + control_image=control_image, + height=1024, + width=1024, + num_inference_steps=30, + guidance_scale=10.0, + generator=torch.Generator().manual_seed(42), +).images[0] +image.save("output.png") +``` + +Depth Control is also possible with a LoRA variant of this condition. The usage is as follows: + +```python +# !pip install git+https://github.com/huggingface/image_gen_aux +import torch +from diffusers import FluxControlPipeline, FluxTransformer2DModel +from diffusers.utils import load_image +from image_gen_aux import DepthPreprocessor + +pipe = FluxControlPipeline.from_pretrained("black-forest-labs/FLUX.1-dev", torch_dtype=torch.bfloat16).to("cuda") +pipe.load_lora_weights("black-forest-labs/FLUX.1-Depth-dev-lora") + +prompt = "A robot made of exotic candies and chocolates of different kinds. The background is filled with confetti and celebratory gifts." +control_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/robot.png") + +processor = DepthPreprocessor.from_pretrained("LiheYoung/depth-anything-large-hf") +control_image = processor(control_image)[0].convert("RGB") + +image = pipe( + prompt=prompt, + control_image=control_image, + height=1024, + width=1024, + num_inference_steps=30, + guidance_scale=10.0, + generator=torch.Generator().manual_seed(42), +).images[0] +image.save("output.png") +``` + +### Redux + +* Flux Redux pipeline is an adapter for FLUX.1 base models. It can be used with both flux-dev and flux-schnell, for image-to-image generation. +* You can first use the `FluxPriorReduxPipeline` to get the `prompt_embeds` and `pooled_prompt_embeds`, and then feed them into the `FluxPipeline` for image-to-image generation. +* When use `FluxPriorReduxPipeline` with a base pipeline, you can set `text_encoder=None` and `text_encoder_2=None` in the base pipeline, in order to save VRAM. + +```python +import torch +from diffusers import FluxPriorReduxPipeline, FluxPipeline +from diffusers.utils import load_image +device = "cuda" +dtype = torch.bfloat16 + + +repo_redux = "black-forest-labs/FLUX.1-Redux-dev" +repo_base = "black-forest-labs/FLUX.1-dev" +pipe_prior_redux = FluxPriorReduxPipeline.from_pretrained(repo_redux, torch_dtype=dtype).to(device) +pipe = FluxPipeline.from_pretrained( + repo_base, + text_encoder=None, + text_encoder_2=None, + torch_dtype=torch.bfloat16 +).to(device) + +image = load_image("https://huggingface.co/datasets/YiYiXu/testing-images/resolve/main/style_ziggy/img5.png") +pipe_prior_output = pipe_prior_redux(image) +images = pipe( + guidance_scale=2.5, + num_inference_steps=50, + generator=torch.Generator("cpu").manual_seed(0), + **pipe_prior_output, +).images +images[0].save("flux-redux.png") +``` + +## Combining Flux Turbo LoRAs with Flux Control, Fill, and Redux + +We can combine Flux Turbo LoRAs with Flux Control and other pipelines like Fill and Redux to enable few-steps' inference. The example below shows how to do that for Flux Control LoRA for depth and turbo LoRA from [`ByteDance/Hyper-SD`](https://hf.co/ByteDance/Hyper-SD). + +```py +from diffusers import FluxControlPipeline +from image_gen_aux import DepthPreprocessor +from diffusers.utils import load_image +from huggingface_hub import hf_hub_download +import torch + +control_pipe = FluxControlPipeline.from_pretrained("black-forest-labs/FLUX.1-dev", torch_dtype=torch.bfloat16) +control_pipe.load_lora_weights("black-forest-labs/FLUX.1-Depth-dev-lora", adapter_name="depth") +control_pipe.load_lora_weights( + hf_hub_download("ByteDance/Hyper-SD", "Hyper-FLUX.1-dev-8steps-lora.safetensors"), adapter_name="hyper-sd" +) +control_pipe.set_adapters(["depth", "hyper-sd"], adapter_weights=[0.85, 0.125]) +control_pipe.enable_model_cpu_offload() + +prompt = "A robot made of exotic candies and chocolates of different kinds. The background is filled with confetti and celebratory gifts." +control_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/robot.png") + +processor = DepthPreprocessor.from_pretrained("LiheYoung/depth-anything-large-hf") +control_image = processor(control_image)[0].convert("RGB") + +image = control_pipe( + prompt=prompt, + control_image=control_image, + height=1024, + width=1024, + num_inference_steps=8, + guidance_scale=10.0, + generator=torch.Generator().manual_seed(42), +).images[0] +image.save("output.png") +``` + +## Note about `unload_lora_weights()` when using Flux LoRAs + +When unloading the Control LoRA weights, call `pipe.unload_lora_weights(reset_to_overwritten_params=True)` to reset the `pipe.transformer` completely back to its original form. The resultant pipeline can then be used with methods like [`DiffusionPipeline.from_pipe`]. More details about this argument are available in [this PR](https://github.com/huggingface/diffusers/pull/10397). + +## IP-Adapter + + + +Check out [IP-Adapter](../../../using-diffusers/ip_adapter) to learn more about how IP-Adapters work. + + + +An IP-Adapter lets you prompt Flux with images, in addition to the text prompt. This is especially useful when describing complex concepts that are difficult to articulate through text alone and you have reference images. + +```python +import torch +from diffusers import FluxPipeline +from diffusers.utils import load_image + +pipe = FluxPipeline.from_pretrained( + "black-forest-labs/FLUX.1-dev", torch_dtype=torch.bfloat16 +).to("cuda") + +image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/flux_ip_adapter_input.jpg").resize((1024, 1024)) + +pipe.load_ip_adapter( + "XLabs-AI/flux-ip-adapter", + weight_name="ip_adapter.safetensors", + image_encoder_pretrained_model_name_or_path="openai/clip-vit-large-patch14" +) +pipe.set_ip_adapter_scale(1.0) + +image = pipe( + width=1024, + height=1024, + prompt="wearing sunglasses", + negative_prompt="", + true_cfg_scale=4.0, + generator=torch.Generator().manual_seed(4444), + ip_adapter_image=image, +).images[0] + +image.save('flux_ip_adapter_output.jpg') +``` + +
+ +
IP-Adapter examples with prompt "wearing sunglasses"
+
+ +## Optimize + +Flux is a very large model and requires ~50GB of RAM/VRAM to load all the modeling components. Enable some of the optimizations below to lower the memory requirements. + +### Group offloading + +[Group offloading](../../optimization/memory#group-offloading) lowers VRAM usage by offloading groups of internal layers rather than the whole model or weights. You need to use [`~hooks.apply_group_offloading`] on all the model components of a pipeline. The `offload_type` parameter allows you to toggle between block and leaf-level offloading. Setting it to `leaf_level` offloads the lowest leaf-level parameters to the CPU instead of offloading at the module-level. + +On CUDA devices that support asynchronous data streaming, set `use_stream=True` to overlap data transfer and computation to accelerate inference. + +> [!TIP] +> It is possible to mix block and leaf-level offloading for different components in a pipeline. + +```py +import torch +from diffusers import FluxPipeline +from diffusers.hooks import apply_group_offloading + +model_id = "black-forest-labs/FLUX.1-dev" +dtype = torch.bfloat16 +pipe = FluxPipeline.from_pretrained( + model_id, + torch_dtype=dtype, +) + +apply_group_offloading( + pipe.transformer, + offload_type="leaf_level", + offload_device=torch.device("cpu"), + onload_device=torch.device("cuda"), + use_stream=True, +) +apply_group_offloading( + pipe.text_encoder, + offload_device=torch.device("cpu"), + onload_device=torch.device("cuda"), + offload_type="leaf_level", + use_stream=True, +) +apply_group_offloading( + pipe.text_encoder_2, + offload_device=torch.device("cpu"), + onload_device=torch.device("cuda"), + offload_type="leaf_level", + use_stream=True, +) +apply_group_offloading( + pipe.vae, + offload_device=torch.device("cpu"), + onload_device=torch.device("cuda"), + offload_type="leaf_level", + use_stream=True, +) + +prompt="A cat wearing sunglasses and working as a lifeguard at pool." + +generator = torch.Generator().manual_seed(181201) +image = pipe( + prompt, + width=576, + height=1024, + num_inference_steps=30, + generator=generator +).images[0] +image +``` + +### Running FP16 inference + +Flux can generate high-quality images with FP16 (i.e. to accelerate inference on Turing/Volta GPUs) but produces different outputs compared to FP32/BF16. The issue is that some activations in the text encoders have to be clipped when running in FP16, which affects the overall image. Forcing text encoders to run with FP32 inference thus removes this output difference. See [here](https://github.com/huggingface/diffusers/pull/9097#issuecomment-2272292516) for details. + +FP16 inference code: +```python +import torch +from diffusers import FluxPipeline + +pipe = FluxPipeline.from_pretrained("black-forest-labs/FLUX.1-schnell", torch_dtype=torch.bfloat16) # can replace schnell with dev +# to run on low vram GPUs (i.e. between 4 and 32 GB VRAM) +pipe.enable_sequential_cpu_offload() +pipe.vae.enable_slicing() +pipe.vae.enable_tiling() + +pipe.to(torch.float16) # casting here instead of in the pipeline constructor because doing so in the constructor loads all models into CPU memory at once + +prompt = "A cat holding a sign that says hello world" +out = pipe( + prompt=prompt, + guidance_scale=0., + height=768, + width=1360, + num_inference_steps=4, + max_sequence_length=256, +).images[0] +out.save("image.png") +``` + +### Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`FluxPipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, FluxTransformer2DModel, FluxPipeline +from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel + +quant_config = BitsAndBytesConfig(load_in_8bit=True) +text_encoder_8bit = T5EncoderModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="text_encoder_2", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = FluxTransformer2DModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +pipeline = FluxPipeline.from_pretrained( + "black-forest-labs/FLUX.1-dev", + text_encoder_2=text_encoder_8bit, + transformer=transformer_8bit, + torch_dtype=torch.float16, + device_map="balanced", +) + +prompt = "a tiny astronaut hatching from an egg on the moon" +image = pipeline(prompt, guidance_scale=3.5, height=768, width=1360, num_inference_steps=50).images[0] +image.save("flux.png") +``` + +## Single File Loading for the `FluxTransformer2DModel` + +The `FluxTransformer2DModel` supports loading checkpoints in the original format shipped by Black Forest Labs. This is also useful when trying to load finetunes or quantized versions of the models that have been published by the community. + + +`FP8` inference can be brittle depending on the GPU type, CUDA version, and `torch` version that you are using. It is recommended that you use the `optimum-quanto` library in order to run FP8 inference on your machine. + + +The following example demonstrates how to run Flux with less than 16GB of VRAM. + +First install `optimum-quanto` + +```shell +pip install optimum-quanto +``` + +Then run the following example + +```python +import torch +from diffusers import FluxTransformer2DModel, FluxPipeline +from transformers import T5EncoderModel, CLIPTextModel +from optimum.quanto import freeze, qfloat8, quantize + +bfl_repo = "black-forest-labs/FLUX.1-dev" +dtype = torch.bfloat16 + +transformer = FluxTransformer2DModel.from_single_file("https://huggingface.co/Kijai/flux-fp8/blob/main/flux1-dev-fp8.safetensors", torch_dtype=dtype) +quantize(transformer, weights=qfloat8) +freeze(transformer) + +text_encoder_2 = T5EncoderModel.from_pretrained(bfl_repo, subfolder="text_encoder_2", torch_dtype=dtype) +quantize(text_encoder_2, weights=qfloat8) +freeze(text_encoder_2) + +pipe = FluxPipeline.from_pretrained(bfl_repo, transformer=None, text_encoder_2=None, torch_dtype=dtype) +pipe.transformer = transformer +pipe.text_encoder_2 = text_encoder_2 + +pipe.enable_model_cpu_offload() + +prompt = "A cat holding a sign that says hello world" +image = pipe( + prompt, + guidance_scale=3.5, + output_type="pil", + num_inference_steps=20, + generator=torch.Generator("cpu").manual_seed(0) +).images[0] + +image.save("flux-fp8-dev.png") +``` + +## FluxPipeline + +[[autodoc]] FluxPipeline + - all + - __call__ + +## FluxImg2ImgPipeline + +[[autodoc]] FluxImg2ImgPipeline + - all + - __call__ + +## FluxInpaintPipeline + +[[autodoc]] FluxInpaintPipeline + - all + - __call__ + + +## FluxControlNetInpaintPipeline + +[[autodoc]] FluxControlNetInpaintPipeline + - all + - __call__ + +## FluxControlNetImg2ImgPipeline + +[[autodoc]] FluxControlNetImg2ImgPipeline + - all + - __call__ + +## FluxControlPipeline + +[[autodoc]] FluxControlPipeline + - all + - __call__ + +## FluxControlImg2ImgPipeline + +[[autodoc]] FluxControlImg2ImgPipeline + - all + - __call__ + +## FluxPriorReduxPipeline + +[[autodoc]] FluxPriorReduxPipeline + - all + - __call__ + +## FluxFillPipeline + +[[autodoc]] FluxFillPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/framepack.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/framepack.md new file mode 100644 index 0000000000000000000000000000000000000000..ba7b2d0dc0f1345af165691cbf23daee8c5f1630 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/framepack.md @@ -0,0 +1,209 @@ + + +# Framepack + +
+ LoRA +
+ +[Packing Input Frame Context in Next-Frame Prediction Models for Video Generation](https://huggingface.co/papers/2504.12626) by Lvmin Zhang and Maneesh Agrawala. + +*We present a neural network structure, FramePack, to train next-frame (or next-frame-section) prediction models for video generation. The FramePack compresses input frames to make the transformer context length a fixed number regardless of the video length. As a result, we are able to process a large number of frames using video diffusion with computation bottleneck similar to image diffusion. This also makes the training video batch sizes significantly higher (batch sizes become comparable to image diffusion training). We also propose an anti-drifting sampling method that generates frames in inverted temporal order with early-established endpoints to avoid exposure bias (error accumulation over iterations). Finally, we show that existing video diffusion models can be finetuned with FramePack, and their visual quality may be improved because the next-frame prediction supports more balanced diffusion schedulers with less extreme flow shift timesteps.* + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## Available models + +| Model name | Description | +|:---|:---| +- [`lllyasviel/FramePackI2V_HY`](https://huggingface.co/lllyasviel/FramePackI2V_HY) | Trained with the "inverted anti-drifting" strategy as described in the paper. Inference requires setting `sampling_type="inverted_anti_drifting"` when running the pipeline. | +- [`lllyasviel/FramePack_F1_I2V_HY_20250503`](https://huggingface.co/lllyasviel/FramePack_F1_I2V_HY_20250503) | Trained with a novel anti-drifting strategy but inference is performed in "vanilla" strategy as described in the paper. Inference requires setting `sampling_type="vanilla"` when running the pipeline. | + +## Usage + +Refer to the pipeline documentation for basic usage examples. The following section contains examples of offloading, different sampling methods, quantization, and more. + +### First and last frame to video + +The following example shows how to use Framepack with start and end image controls, using the inverted anti-drifiting sampling model. + +```python +import torch +from diffusers import HunyuanVideoFramepackPipeline, HunyuanVideoFramepackTransformer3DModel +from diffusers.utils import export_to_video, load_image +from transformers import SiglipImageProcessor, SiglipVisionModel + +transformer = HunyuanVideoFramepackTransformer3DModel.from_pretrained( + "lllyasviel/FramePackI2V_HY", torch_dtype=torch.bfloat16 +) +feature_extractor = SiglipImageProcessor.from_pretrained( + "lllyasviel/flux_redux_bfl", subfolder="feature_extractor" +) +image_encoder = SiglipVisionModel.from_pretrained( + "lllyasviel/flux_redux_bfl", subfolder="image_encoder", torch_dtype=torch.float16 +) +pipe = HunyuanVideoFramepackPipeline.from_pretrained( + "hunyuanvideo-community/HunyuanVideo", + transformer=transformer, + feature_extractor=feature_extractor, + image_encoder=image_encoder, + torch_dtype=torch.float16, +) + +# Enable memory optimizations +pipe.enable_model_cpu_offload() +pipe.vae.enable_tiling() + +prompt = "CG animation style, a small blue bird takes off from the ground, flapping its wings. The bird's feathers are delicate, with a unique pattern on its chest. The background shows a blue sky with white clouds under bright sunshine. The camera follows the bird upward, capturing its flight and the vastness of the sky from a close-up, low-angle perspective." +first_image = load_image( + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/flf2v_input_first_frame.png" +) +last_image = load_image( + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/flf2v_input_last_frame.png" +) +output = pipe( + image=first_image, + last_image=last_image, + prompt=prompt, + height=512, + width=512, + num_frames=91, + num_inference_steps=30, + guidance_scale=9.0, + generator=torch.Generator().manual_seed(0), + sampling_type="inverted_anti_drifting", +).frames[0] +export_to_video(output, "output.mp4", fps=30) +``` + +### Vanilla sampling + +The following example shows how to use Framepack with the F1 model trained with vanilla sampling but new regulation approach for anti-drifting. + +```python +import torch +from diffusers import HunyuanVideoFramepackPipeline, HunyuanVideoFramepackTransformer3DModel +from diffusers.utils import export_to_video, load_image +from transformers import SiglipImageProcessor, SiglipVisionModel + +transformer = HunyuanVideoFramepackTransformer3DModel.from_pretrained( + "lllyasviel/FramePack_F1_I2V_HY_20250503", torch_dtype=torch.bfloat16 +) +feature_extractor = SiglipImageProcessor.from_pretrained( + "lllyasviel/flux_redux_bfl", subfolder="feature_extractor" +) +image_encoder = SiglipVisionModel.from_pretrained( + "lllyasviel/flux_redux_bfl", subfolder="image_encoder", torch_dtype=torch.float16 +) +pipe = HunyuanVideoFramepackPipeline.from_pretrained( + "hunyuanvideo-community/HunyuanVideo", + transformer=transformer, + feature_extractor=feature_extractor, + image_encoder=image_encoder, + torch_dtype=torch.float16, +) + +# Enable memory optimizations +pipe.enable_model_cpu_offload() +pipe.vae.enable_tiling() + +image = load_image( + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/penguin.png" +) +output = pipe( + image=image, + prompt="A penguin dancing in the snow", + height=832, + width=480, + num_frames=91, + num_inference_steps=30, + guidance_scale=9.0, + generator=torch.Generator().manual_seed(0), + sampling_type="vanilla", +).frames[0] +export_to_video(output, "output.mp4", fps=30) +``` + +### Group offloading + +Group offloading ([`~hooks.apply_group_offloading`]) provides aggressive memory optimizations for offloading internal parts of any model to the CPU, with possibly no additional overhead to generation time. If you have very low VRAM available, this approach may be suitable for you depending on the amount of CPU RAM available. + +```python +import torch +from diffusers import HunyuanVideoFramepackPipeline, HunyuanVideoFramepackTransformer3DModel +from diffusers.hooks import apply_group_offloading +from diffusers.utils import export_to_video, load_image +from transformers import SiglipImageProcessor, SiglipVisionModel + +transformer = HunyuanVideoFramepackTransformer3DModel.from_pretrained( + "lllyasviel/FramePack_F1_I2V_HY_20250503", torch_dtype=torch.bfloat16 +) +feature_extractor = SiglipImageProcessor.from_pretrained( + "lllyasviel/flux_redux_bfl", subfolder="feature_extractor" +) +image_encoder = SiglipVisionModel.from_pretrained( + "lllyasviel/flux_redux_bfl", subfolder="image_encoder", torch_dtype=torch.float16 +) +pipe = HunyuanVideoFramepackPipeline.from_pretrained( + "hunyuanvideo-community/HunyuanVideo", + transformer=transformer, + feature_extractor=feature_extractor, + image_encoder=image_encoder, + torch_dtype=torch.float16, +) + +# Enable group offloading +onload_device = torch.device("cuda") +offload_device = torch.device("cpu") +list(map( + lambda x: apply_group_offloading(x, onload_device, offload_device, offload_type="leaf_level", use_stream=True, low_cpu_mem_usage=True), + [pipe.text_encoder, pipe.text_encoder_2, pipe.transformer] +)) +pipe.image_encoder.to(onload_device) +pipe.vae.to(onload_device) +pipe.vae.enable_tiling() + +image = load_image( + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/penguin.png" +) +output = pipe( + image=image, + prompt="A penguin dancing in the snow", + height=832, + width=480, + num_frames=91, + num_inference_steps=30, + guidance_scale=9.0, + generator=torch.Generator().manual_seed(0), + sampling_type="vanilla", +).frames[0] +print(f"Max memory: {torch.cuda.max_memory_allocated() / 1024**3:.3f} GB") +export_to_video(output, "output.mp4", fps=30) +``` + +## HunyuanVideoFramepackPipeline + +[[autodoc]] HunyuanVideoFramepackPipeline + - all + - __call__ + +## HunyuanVideoPipelineOutput + +[[autodoc]] pipelines.hunyuan_video.pipeline_output.HunyuanVideoPipelineOutput + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/hidream.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/hidream.md new file mode 100644 index 0000000000000000000000000000000000000000..f728d3d90f4c9290fd83b9915f13eafec6a0772a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/hidream.md @@ -0,0 +1,43 @@ + + +# HiDreamImage + +[HiDream-I1](https://huggingface.co/HiDream-ai) by HiDream.ai + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## Available models + +The following models are available for the [`HiDreamImagePipeline`](text-to-image) pipeline: + +| Model name | Description | +|:---|:---| +| [`HiDream-ai/HiDream-I1-Full`](https://huggingface.co/HiDream-ai/HiDream-I1-Full) | - | +| [`HiDream-ai/HiDream-I1-Dev`](https://huggingface.co/HiDream-ai/HiDream-I1-Dev) | - | +| [`HiDream-ai/HiDream-I1-Fast`](https://huggingface.co/HiDream-ai/HiDream-I1-Fast) | - | + +## HiDreamImagePipeline + +[[autodoc]] HiDreamImagePipeline + - all + - __call__ + +## HiDreamImagePipelineOutput + +[[autodoc]] pipelines.hidream_image.pipeline_output.HiDreamImagePipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/hunyuan_video.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/hunyuan_video.md new file mode 100644 index 0000000000000000000000000000000000000000..5d068c8b6ef8168d062424b69f875d8bc1c8e2b2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/hunyuan_video.md @@ -0,0 +1,95 @@ + + +# HunyuanVideo + +
+ LoRA +
+ +[HunyuanVideo](https://www.arxiv.org/abs/2412.03603) by Tencent. + +*Recent advancements in video generation have significantly impacted daily life for both individuals and industries. However, the leading video generation models remain closed-source, resulting in a notable performance gap between industry capabilities and those available to the public. In this report, we introduce HunyuanVideo, an innovative open-source video foundation model that demonstrates performance in video generation comparable to, or even surpassing, that of leading closed-source models. HunyuanVideo encompasses a comprehensive framework that integrates several key elements, including data curation, advanced architectural design, progressive model scaling and training, and an efficient infrastructure tailored for large-scale model training and inference. As a result, we successfully trained a video generative model with over 13 billion parameters, making it the largest among all open-source models. We conducted extensive experiments and implemented a series of targeted designs to ensure high visual quality, motion dynamics, text-video alignment, and advanced filming techniques. According to evaluations by professionals, HunyuanVideo outperforms previous state-of-the-art models, including Runway Gen-3, Luma 1.6, and three top-performing Chinese video generative models. By releasing the code for the foundation model and its applications, we aim to bridge the gap between closed-source and open-source communities. This initiative will empower individuals within the community to experiment with their ideas, fostering a more dynamic and vibrant video generation ecosystem. The code is publicly available at [this https URL](https://github.com/tencent/HunyuanVideo).* + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +Recommendations for inference: +- Both text encoders should be in `torch.float16`. +- Transformer should be in `torch.bfloat16`. +- VAE should be in `torch.float16`. +- `num_frames` should be of the form `4 * k + 1`, for example `49` or `129`. +- For smaller resolution videos, try lower values of `shift` (between `2.0` to `5.0`) in the [Scheduler](https://huggingface.co/docs/diffusers/main/en/api/schedulers/flow_match_euler_discrete#diffusers.FlowMatchEulerDiscreteScheduler.shift). For larger resolution images, try higher values (between `7.0` and `12.0`). The default value is `7.0` for HunyuanVideo. +- For more information about supported resolutions and other details, please refer to the original repository [here](https://github.com/Tencent/HunyuanVideo/). + +## Available models + +The following models are available for the [`HunyuanVideoPipeline`](text-to-video) pipeline: + +| Model name | Description | +|:---|:---| +| [`hunyuanvideo-community/HunyuanVideo`](https://huggingface.co/hunyuanvideo-community/HunyuanVideo) | Official HunyuanVideo (guidance-distilled). Performs best at multiple resolutions and frames. Performs best with `guidance_scale=6.0`, `true_cfg_scale=1.0` and without a negative prompt. | +| [`https://huggingface.co/Skywork/SkyReels-V1-Hunyuan-T2V`](https://huggingface.co/Skywork/SkyReels-V1-Hunyuan-T2V) | Skywork's custom finetune of HunyuanVideo (de-distilled). Performs best with `97x544x960` resolution, `guidance_scale=1.0`, `true_cfg_scale=6.0` and a negative prompt. | + +The following models are available for the image-to-video pipeline: + +| Model name | Description | +|:---|:---| +| [`Skywork/SkyReels-V1-Hunyuan-I2V`](https://huggingface.co/Skywork/SkyReels-V1-Hunyuan-I2V) | Skywork's custom finetune of HunyuanVideo (de-distilled). Performs best with `97x544x960` resolution. Performs best at `97x544x960` resolution, `guidance_scale=1.0`, `true_cfg_scale=6.0` and a negative prompt. | +| [`hunyuanvideo-community/HunyuanVideo-I2V-33ch`](https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V) | Tecent's official HunyuanVideo 33-channel I2V model. Performs best at resolutions of 480, 720, 960, 1280. A higher `shift` value when initializing the scheduler is recommended (good values are between 7 and 20). | +| [`hunyuanvideo-community/HunyuanVideo-I2V`](https://huggingface.co/hunyuanvideo-community/HunyuanVideo-I2V) | Tecent's official HunyuanVideo 16-channel I2V model. Performs best at resolutions of 480, 720, 960, 1280. A higher `shift` value when initializing the scheduler is recommended (good values are between 7 and 20) | + +## Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`HunyuanVideoPipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, HunyuanVideoTransformer3DModel, HunyuanVideoPipeline +from diffusers.utils import export_to_video + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = HunyuanVideoTransformer3DModel.from_pretrained( + "hunyuanvideo-community/HunyuanVideo", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.bfloat16, +) + +pipeline = HunyuanVideoPipeline.from_pretrained( + "hunyuanvideo-community/HunyuanVideo", + transformer=transformer_8bit, + torch_dtype=torch.float16, + device_map="balanced", +) + +prompt = "A cat walks on the grass, realistic style." +video = pipeline(prompt=prompt, num_frames=61, num_inference_steps=30).frames[0] +export_to_video(video, "cat.mp4", fps=15) +``` + +## HunyuanVideoPipeline + +[[autodoc]] HunyuanVideoPipeline + - all + - __call__ + +## HunyuanVideoPipelineOutput + +[[autodoc]] pipelines.hunyuan_video.pipeline_output.HunyuanVideoPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/hunyuandit.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/hunyuandit.md new file mode 100644 index 0000000000000000000000000000000000000000..9260206f4feaea38db5ee27fa47eba17f5117744 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/hunyuandit.md @@ -0,0 +1,101 @@ + + +# Hunyuan-DiT +![chinese elements understanding](https://github.com/gnobitab/diffusers-hunyuan/assets/1157982/39b99036-c3cb-4f16-bb1a-40ec25eda573) + +[Hunyuan-DiT : A Powerful Multi-Resolution Diffusion Transformer with Fine-Grained Chinese Understanding](https://huggingface.co/papers/2405.08748) from Tencent Hunyuan. + +The abstract from the paper is: + +*We present Hunyuan-DiT, a text-to-image diffusion transformer with fine-grained understanding of both English and Chinese. To construct Hunyuan-DiT, we carefully design the transformer structure, text encoder, and positional encoding. We also build from scratch a whole data pipeline to update and evaluate data for iterative model optimization. For fine-grained language understanding, we train a Multimodal Large Language Model to refine the captions of the images. Finally, Hunyuan-DiT can perform multi-turn multimodal dialogue with users, generating and refining images according to the context. Through our holistic human evaluation protocol with more than 50 professional human evaluators, Hunyuan-DiT sets a new state-of-the-art in Chinese-to-image generation compared with other open-source models.* + + +You can find the original codebase at [Tencent/HunyuanDiT](https://github.com/Tencent/HunyuanDiT) and all the available checkpoints at [Tencent-Hunyuan](https://huggingface.co/Tencent-Hunyuan/HunyuanDiT). + +**Highlights**: HunyuanDiT supports Chinese/English-to-image, multi-resolution generation. + +HunyuanDiT has the following components: +* It uses a diffusion transformer as the backbone +* It combines two text encoders, a bilingual CLIP and a multilingual T5 encoder + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + + + +You can further improve generation quality by passing the generated image from [`HungyuanDiTPipeline`] to the [SDXL refiner](../../using-diffusers/sdxl#base-to-refiner-model) model. + + + +## Optimization + +You can optimize the pipeline's runtime and memory consumption with torch.compile and feed-forward chunking. To learn about other optimization methods, check out the [Speed up inference](../../optimization/fp16) and [Reduce memory usage](../../optimization/memory) guides. + +### Inference + +Use [`torch.compile`](https://huggingface.co/docs/diffusers/main/en/tutorials/fast_diffusion#torchcompile) to reduce the inference latency. + +First, load the pipeline: + +```python +from diffusers import HunyuanDiTPipeline +import torch + +pipeline = HunyuanDiTPipeline.from_pretrained( + "Tencent-Hunyuan/HunyuanDiT-Diffusers", torch_dtype=torch.float16 +).to("cuda") +``` + +Then change the memory layout of the pipelines `transformer` and `vae` components to `torch.channels-last`: + +```python +pipeline.transformer.to(memory_format=torch.channels_last) +pipeline.vae.to(memory_format=torch.channels_last) +``` + +Finally, compile the components and run inference: + +```python +pipeline.transformer = torch.compile(pipeline.transformer, mode="max-autotune", fullgraph=True) +pipeline.vae.decode = torch.compile(pipeline.vae.decode, mode="max-autotune", fullgraph=True) + +image = pipeline(prompt="一个宇航员在骑马").images[0] +``` + +The [benchmark](https://gist.github.com/sayakpaul/29d3a14905cfcbf611fe71ebd22e9b23) results on a 80GB A100 machine are: + +```bash +With torch.compile(): Average inference time: 12.470 seconds. +Without torch.compile(): Average inference time: 20.570 seconds. +``` + +### Memory optimization + +By loading the T5 text encoder in 8 bits, you can run the pipeline in just under 6 GBs of GPU VRAM. Refer to [this script](https://gist.github.com/sayakpaul/3154605f6af05b98a41081aaba5ca43e) for details. + +Furthermore, you can use the [`~HunyuanDiT2DModel.enable_forward_chunking`] method to reduce memory usage. Feed-forward chunking runs the feed-forward layers in a transformer block in a loop instead of all at once. This gives you a trade-off between memory consumption and inference runtime. + +```diff ++ pipeline.transformer.enable_forward_chunking(chunk_size=1, dim=1) +``` + + +## HunyuanDiTPipeline + +[[autodoc]] HunyuanDiTPipeline + - all + - __call__ + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/i2vgenxl.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/i2vgenxl.md new file mode 100644 index 0000000000000000000000000000000000000000..8ce0b5f654bc42ce3dfb0d2378f971bfca9b002f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/i2vgenxl.md @@ -0,0 +1,58 @@ + + +# I2VGen-XL + +[I2VGen-XL: High-Quality Image-to-Video Synthesis via Cascaded Diffusion Models](https://hf.co/papers/2311.04145.pdf) by Shiwei Zhang, Jiayu Wang, Yingya Zhang, Kang Zhao, Hangjie Yuan, Zhiwu Qin, Xiang Wang, Deli Zhao, and Jingren Zhou. + +The abstract from the paper is: + +*Video synthesis has recently made remarkable strides benefiting from the rapid development of diffusion models. However, it still encounters challenges in terms of semantic accuracy, clarity and spatio-temporal continuity. They primarily arise from the scarcity of well-aligned text-video data and the complex inherent structure of videos, making it difficult for the model to simultaneously ensure semantic and qualitative excellence. In this report, we propose a cascaded I2VGen-XL approach that enhances model performance by decoupling these two factors and ensures the alignment of the input data by utilizing static images as a form of crucial guidance. I2VGen-XL consists of two stages: i) the base stage guarantees coherent semantics and preserves content from input images by using two hierarchical encoders, and ii) the refinement stage enhances the video's details by incorporating an additional brief text and improves the resolution to 1280×720. To improve the diversity, we collect around 35 million single-shot text-video pairs and 6 billion text-image pairs to optimize the model. By this means, I2VGen-XL can simultaneously enhance the semantic accuracy, continuity of details and clarity of generated videos. Through extensive experiments, we have investigated the underlying principles of I2VGen-XL and compared it with current top methods, which can demonstrate its effectiveness on diverse data. The source code and models will be publicly available at [this https URL](https://i2vgen-xl.github.io/).* + +The original codebase can be found [here](https://github.com/ali-vilab/i2vgen-xl/). The model checkpoints can be found [here](https://huggingface.co/ali-vilab/). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. Also, to know more about reducing the memory usage of this pipeline, refer to the ["Reduce memory usage"] section [here](../../using-diffusers/svd#reduce-memory-usage). + + + +Sample output with I2VGenXL: + + + + + +
+ library. +
+ library +
+ +## Notes + +* I2VGenXL always uses a `clip_skip` value of 1. This means it leverages the penultimate layer representations from the text encoder of CLIP. +* It can generate videos of quality that is often on par with [Stable Video Diffusion](../../using-diffusers/svd) (SVD). +* Unlike SVD, it additionally accepts text prompts as inputs. +* It can generate higher resolution videos. +* When using the [`DDIMScheduler`] (which is default for this pipeline), less than 50 steps for inference leads to bad results. +* This implementation is 1-stage variant of I2VGenXL. The main figure in the [I2VGen-XL](https://huggingface.co/papers/2311.04145) paper shows a 2-stage variant, however, 1-stage variant works well. See [this discussion](https://github.com/huggingface/diffusers/discussions/7952) for more details. + +## I2VGenXLPipeline +[[autodoc]] I2VGenXLPipeline + - all + - __call__ + +## I2VGenXLPipelineOutput +[[autodoc]] pipelines.i2vgen_xl.pipeline_i2vgen_xl.I2VGenXLPipelineOutput \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/kandinsky.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/kandinsky.md new file mode 100644 index 0000000000000000000000000000000000000000..72cbf3fb474d3a9d012773ba0de2767a4f8261b8 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/kandinsky.md @@ -0,0 +1,73 @@ + + +# Kandinsky 2.1 + +Kandinsky 2.1 is created by [Arseniy Shakhmatov](https://github.com/cene555), [Anton Razzhigaev](https://github.com/razzant), [Aleksandr Nikolich](https://github.com/AlexWortega), [Vladimir Arkhipkin](https://github.com/oriBetelgeuse), [Igor Pavlov](https://github.com/boomb0om), [Andrey Kuznetsov](https://github.com/kuznetsoffandrey), and [Denis Dimitrov](https://github.com/denndimitrov). + +The description from it's GitHub page is: + +*Kandinsky 2.1 inherits best practicies from Dall-E 2 and Latent diffusion, while introducing some new ideas. As text and image encoder it uses CLIP model and diffusion image prior (mapping) between latent spaces of CLIP modalities. This approach increases the visual performance of the model and unveils new horizons in blending images and text-guided image manipulation.* + +The original codebase can be found at [ai-forever/Kandinsky-2](https://github.com/ai-forever/Kandinsky-2). + + + +Check out the [Kandinsky Community](https://huggingface.co/kandinsky-community) organization on the Hub for the official model checkpoints for tasks like text-to-image, image-to-image, and inpainting. + + + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## KandinskyPriorPipeline + +[[autodoc]] KandinskyPriorPipeline + - all + - __call__ + - interpolate + +## KandinskyPipeline + +[[autodoc]] KandinskyPipeline + - all + - __call__ + +## KandinskyCombinedPipeline + +[[autodoc]] KandinskyCombinedPipeline + - all + - __call__ + +## KandinskyImg2ImgPipeline + +[[autodoc]] KandinskyImg2ImgPipeline + - all + - __call__ + +## KandinskyImg2ImgCombinedPipeline + +[[autodoc]] KandinskyImg2ImgCombinedPipeline + - all + - __call__ + +## KandinskyInpaintPipeline + +[[autodoc]] KandinskyInpaintPipeline + - all + - __call__ + +## KandinskyInpaintCombinedPipeline + +[[autodoc]] KandinskyInpaintCombinedPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/kandinsky3.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/kandinsky3.md new file mode 100644 index 0000000000000000000000000000000000000000..f4bea2b117d313aa25ccda4d4180b6cb0e58072c --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/kandinsky3.md @@ -0,0 +1,53 @@ + + +# Kandinsky 3 + +
+ LoRA +
+ +Kandinsky 3 is created by [Vladimir Arkhipkin](https://github.com/oriBetelgeuse),[Anastasia Maltseva](https://github.com/NastyaMittseva),[Igor Pavlov](https://github.com/boomb0om),[Andrei Filatov](https://github.com/anvilarth),[Arseniy Shakhmatov](https://github.com/cene555),[Andrey Kuznetsov](https://github.com/kuznetsoffandrey),[Denis Dimitrov](https://github.com/denndimitrov), [Zein Shaheen](https://github.com/zeinsh) + +The description from it's GitHub page: + +*Kandinsky 3.0 is an open-source text-to-image diffusion model built upon the Kandinsky2-x model family. In comparison to its predecessors, enhancements have been made to the text understanding and visual quality of the model, achieved by increasing the size of the text encoder and Diffusion U-Net models, respectively.* + +Its architecture includes 3 main components: +1. [FLAN-UL2](https://huggingface.co/google/flan-ul2), which is an encoder decoder model based on the T5 architecture. +2. New U-Net architecture featuring BigGAN-deep blocks doubles depth while maintaining the same number of parameters. +3. Sber-MoVQGAN is a decoder proven to have superior results in image restoration. + + + +The original codebase can be found at [ai-forever/Kandinsky-3](https://github.com/ai-forever/Kandinsky-3). + + + +Check out the [Kandinsky Community](https://huggingface.co/kandinsky-community) organization on the Hub for the official model checkpoints for tasks like text-to-image, image-to-image, and inpainting. + + + + + +Make sure to check out the schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## Kandinsky3Pipeline + +[[autodoc]] Kandinsky3Pipeline + - all + - __call__ + +## Kandinsky3Img2ImgPipeline + +[[autodoc]] Kandinsky3Img2ImgPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/kandinsky_v22.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/kandinsky_v22.md new file mode 100644 index 0000000000000000000000000000000000000000..f097a085ef7fc653f3dfde2a03617d67250088f8 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/kandinsky_v22.md @@ -0,0 +1,92 @@ + + +# Kandinsky 2.2 + +Kandinsky 2.2 is created by [Arseniy Shakhmatov](https://github.com/cene555), [Anton Razzhigaev](https://github.com/razzant), [Aleksandr Nikolich](https://github.com/AlexWortega), [Vladimir Arkhipkin](https://github.com/oriBetelgeuse), [Igor Pavlov](https://github.com/boomb0om), [Andrey Kuznetsov](https://github.com/kuznetsoffandrey), and [Denis Dimitrov](https://github.com/denndimitrov). + +The description from it's GitHub page is: + +*Kandinsky 2.2 brings substantial improvements upon its predecessor, Kandinsky 2.1, by introducing a new, more powerful image encoder - CLIP-ViT-G and the ControlNet support. The switch to CLIP-ViT-G as the image encoder significantly increases the model's capability to generate more aesthetic pictures and better understand text, thus enhancing the model's overall performance. The addition of the ControlNet mechanism allows the model to effectively control the process of generating images. This leads to more accurate and visually appealing outputs and opens new possibilities for text-guided image manipulation.* + +The original codebase can be found at [ai-forever/Kandinsky-2](https://github.com/ai-forever/Kandinsky-2). + + + +Check out the [Kandinsky Community](https://huggingface.co/kandinsky-community) organization on the Hub for the official model checkpoints for tasks like text-to-image, image-to-image, and inpainting. + + + + + +Make sure to check out the schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## KandinskyV22PriorPipeline + +[[autodoc]] KandinskyV22PriorPipeline + - all + - __call__ + - interpolate + +## KandinskyV22Pipeline + +[[autodoc]] KandinskyV22Pipeline + - all + - __call__ + +## KandinskyV22CombinedPipeline + +[[autodoc]] KandinskyV22CombinedPipeline + - all + - __call__ + +## KandinskyV22ControlnetPipeline + +[[autodoc]] KandinskyV22ControlnetPipeline + - all + - __call__ + +## KandinskyV22PriorEmb2EmbPipeline + +[[autodoc]] KandinskyV22PriorEmb2EmbPipeline + - all + - __call__ + - interpolate + +## KandinskyV22Img2ImgPipeline + +[[autodoc]] KandinskyV22Img2ImgPipeline + - all + - __call__ + +## KandinskyV22Img2ImgCombinedPipeline + +[[autodoc]] KandinskyV22Img2ImgCombinedPipeline + - all + - __call__ + +## KandinskyV22ControlnetImg2ImgPipeline + +[[autodoc]] KandinskyV22ControlnetImg2ImgPipeline + - all + - __call__ + +## KandinskyV22InpaintPipeline + +[[autodoc]] KandinskyV22InpaintPipeline + - all + - __call__ + +## KandinskyV22InpaintCombinedPipeline + +[[autodoc]] KandinskyV22InpaintCombinedPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/kolors.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/kolors.md new file mode 100644 index 0000000000000000000000000000000000000000..8913a2db7925f8341e5d82f1827f9c80dbe2afee --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/kolors.md @@ -0,0 +1,120 @@ + + +# Kolors: Effective Training of Diffusion Model for Photorealistic Text-to-Image Synthesis + +
+ LoRA + MPS +
+ +![](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/kolors/kolors_header_collage.png) + +Kolors is a large-scale text-to-image generation model based on latent diffusion, developed by [the Kuaishou Kolors team](https://github.com/Kwai-Kolors/Kolors). Trained on billions of text-image pairs, Kolors exhibits significant advantages over both open-source and closed-source models in visual quality, complex semantic accuracy, and text rendering for both Chinese and English characters. Furthermore, Kolors supports both Chinese and English inputs, demonstrating strong performance in understanding and generating Chinese-specific content. For more details, please refer to this [technical report](https://github.com/Kwai-Kolors/Kolors/blob/master/imgs/Kolors_paper.pdf). + +The abstract from the technical report is: + +*We present Kolors, a latent diffusion model for text-to-image synthesis, characterized by its profound understanding of both English and Chinese, as well as an impressive degree of photorealism. There are three key insights contributing to the development of Kolors. Firstly, unlike large language model T5 used in Imagen and Stable Diffusion 3, Kolors is built upon the General Language Model (GLM), which enhances its comprehension capabilities in both English and Chinese. Moreover, we employ a multimodal large language model to recaption the extensive training dataset for fine-grained text understanding. These strategies significantly improve Kolors’ ability to comprehend intricate semantics, particularly those involving multiple entities, and enable its advanced text rendering capabilities. Secondly, we divide the training of Kolors into two phases: the concept learning phase with broad knowledge and the quality improvement phase with specifically curated high-aesthetic data. Furthermore, we investigate the critical role of the noise schedule and introduce a novel schedule to optimize high-resolution image generation. These strategies collectively enhance the visual appeal of the generated high-resolution images. Lastly, we propose a category-balanced benchmark KolorsPrompts, which serves as a guide for the training and evaluation of Kolors. Consequently, even when employing the commonly used U-Net backbone, Kolors has demonstrated remarkable performance in human evaluations, surpassing the existing open-source models and achieving Midjourney-v6 level performance, especially in terms of visual appeal. We will release the code and weights of Kolors at , and hope that it will benefit future research and applications in the visual generation community.* + +## Usage Example + +```python +import torch + +from diffusers import DPMSolverMultistepScheduler, KolorsPipeline + +pipe = KolorsPipeline.from_pretrained("Kwai-Kolors/Kolors-diffusers", torch_dtype=torch.float16, variant="fp16") +pipe.to("cuda") +pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config, use_karras_sigmas=True) + +image = pipe( + prompt='一张瓢虫的照片,微距,变焦,高质量,电影,拿着一个牌子,写着"可图"', + negative_prompt="", + guidance_scale=6.5, + num_inference_steps=25, +).images[0] + +image.save("kolors_sample.png") +``` + +### IP Adapter + +Kolors needs a different IP Adapter to work, and it uses [Openai-CLIP-336](https://huggingface.co/openai/clip-vit-large-patch14-336) as an image encoder. + + + +Using an IP Adapter with Kolors requires more than 24GB of VRAM. To use it, we recommend using [`~DiffusionPipeline.enable_model_cpu_offload`] on consumer GPUs. + + + + + +While Kolors is integrated in Diffusers, you need to load the image encoder from a revision to use the safetensor files. You can still use the main branch of the original repository if you're comfortable loading pickle checkpoints. + + + +```python +import torch +from transformers import CLIPVisionModelWithProjection + +from diffusers import DPMSolverMultistepScheduler, KolorsPipeline +from diffusers.utils import load_image + +image_encoder = CLIPVisionModelWithProjection.from_pretrained( + "Kwai-Kolors/Kolors-IP-Adapter-Plus", + subfolder="image_encoder", + low_cpu_mem_usage=True, + torch_dtype=torch.float16, + revision="refs/pr/4", +) + +pipe = KolorsPipeline.from_pretrained( + "Kwai-Kolors/Kolors-diffusers", image_encoder=image_encoder, torch_dtype=torch.float16, variant="fp16" +) +pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config, use_karras_sigmas=True) + +pipe.load_ip_adapter( + "Kwai-Kolors/Kolors-IP-Adapter-Plus", + subfolder="", + weight_name="ip_adapter_plus_general.safetensors", + revision="refs/pr/4", + image_encoder_folder=None, +) +pipe.enable_model_cpu_offload() + +ipa_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/kolors/cat_square.png") + +image = pipe( + prompt="best quality, high quality", + negative_prompt="", + guidance_scale=6.5, + num_inference_steps=25, + ip_adapter_image=ipa_image, +).images[0] + +image.save("kolors_ipa_sample.png") +``` + +## KolorsPipeline + +[[autodoc]] KolorsPipeline + +- all +- __call__ + +## KolorsImg2ImgPipeline + +[[autodoc]] KolorsImg2ImgPipeline + +- all +- __call__ + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/latent_consistency_models.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/latent_consistency_models.md new file mode 100644 index 0000000000000000000000000000000000000000..a4d3bad0a7ac248a8293f66f7a9954cb6ed567db --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/latent_consistency_models.md @@ -0,0 +1,56 @@ + + +# Latent Consistency Models + +
+ LoRA +
+ +Latent Consistency Models (LCMs) were proposed in [Latent Consistency Models: Synthesizing High-Resolution Images with Few-Step Inference](https://huggingface.co/papers/2310.04378) by Simian Luo, Yiqin Tan, Longbo Huang, Jian Li, and Hang Zhao. + +The abstract of the paper is as follows: + +*Latent Diffusion models (LDMs) have achieved remarkable results in synthesizing high-resolution images. However, the iterative sampling process is computationally intensive and leads to slow generation. Inspired by Consistency Models (song et al.), we propose Latent Consistency Models (LCMs), enabling swift inference with minimal steps on any pre-trained LDMs, including Stable Diffusion (rombach et al). Viewing the guided reverse diffusion process as solving an augmented probability flow ODE (PF-ODE), LCMs are designed to directly predict the solution of such ODE in latent space, mitigating the need for numerous iterations and allowing rapid, high-fidelity sampling. Efficiently distilled from pre-trained classifier-free guided diffusion models, a high-quality 768 x 768 2~4-step LCM takes only 32 A100 GPU hours for training. Furthermore, we introduce Latent Consistency Fine-tuning (LCF), a novel method that is tailored for fine-tuning LCMs on customized image datasets. Evaluation on the LAION-5B-Aesthetics dataset demonstrates that LCMs achieve state-of-the-art text-to-image generation performance with few-step inference. Project Page: [this https URL](https://latent-consistency-models.github.io/).* + +A demo for the [SimianLuo/LCM_Dreamshaper_v7](https://huggingface.co/SimianLuo/LCM_Dreamshaper_v7) checkpoint can be found [here](https://huggingface.co/spaces/SimianLuo/Latent_Consistency_Model). + +The pipelines were contributed by [luosiallen](https://luosiallen.github.io/), [nagolinc](https://github.com/nagolinc), and [dg845](https://github.com/dg845). + + +## LatentConsistencyModelPipeline + +[[autodoc]] LatentConsistencyModelPipeline + - all + - __call__ + - enable_freeu + - disable_freeu + - enable_vae_slicing + - disable_vae_slicing + - enable_vae_tiling + - disable_vae_tiling + +## LatentConsistencyModelImg2ImgPipeline + +[[autodoc]] LatentConsistencyModelImg2ImgPipeline + - all + - __call__ + - enable_freeu + - disable_freeu + - enable_vae_slicing + - disable_vae_slicing + - enable_vae_tiling + - disable_vae_tiling + +## StableDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/latent_diffusion.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/latent_diffusion.md new file mode 100644 index 0000000000000000000000000000000000000000..e5cc7c1ab069a21e82b96b1a84dcfdd67f4fbea9 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/latent_diffusion.md @@ -0,0 +1,40 @@ + + +# Latent Diffusion + +Latent Diffusion was proposed in [High-Resolution Image Synthesis with Latent Diffusion Models](https://huggingface.co/papers/2112.10752) by Robin Rombach, Andreas Blattmann, Dominik Lorenz, Patrick Esser, Björn Ommer. + +The abstract from the paper is: + +*By decomposing the image formation process into a sequential application of denoising autoencoders, diffusion models (DMs) achieve state-of-the-art synthesis results on image data and beyond. Additionally, their formulation allows for a guiding mechanism to control the image generation process without retraining. However, since these models typically operate directly in pixel space, optimization of powerful DMs often consumes hundreds of GPU days and inference is expensive due to sequential evaluations. To enable DM training on limited computational resources while retaining their quality and flexibility, we apply them in the latent space of powerful pretrained autoencoders. In contrast to previous work, training diffusion models on such a representation allows for the first time to reach a near-optimal point between complexity reduction and detail preservation, greatly boosting visual fidelity. By introducing cross-attention layers into the model architecture, we turn diffusion models into powerful and flexible generators for general conditioning inputs such as text or bounding boxes and high-resolution synthesis becomes possible in a convolutional manner. Our latent diffusion models (LDMs) achieve a new state of the art for image inpainting and highly competitive performance on various tasks, including unconditional image generation, semantic scene synthesis, and super-resolution, while significantly reducing computational requirements compared to pixel-based DMs.* + +The original codebase can be found at [CompVis/latent-diffusion](https://github.com/CompVis/latent-diffusion). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## LDMTextToImagePipeline +[[autodoc]] LDMTextToImagePipeline + - all + - __call__ + +## LDMSuperResolutionPipeline +[[autodoc]] LDMSuperResolutionPipeline + - all + - __call__ + +## ImagePipelineOutput +[[autodoc]] pipelines.ImagePipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/latte.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/latte.md new file mode 100644 index 0000000000000000000000000000000000000000..ed688b24324e2f9b52656ed7efd31364fb5f81de --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/latte.md @@ -0,0 +1,118 @@ + + +# Latte + +![latte text-to-video](https://github.com/Vchitect/Latte/blob/52bc0029899babbd6e9250384c83d8ed2670ff7a/visuals/latte.gif?raw=true) + +[Latte: Latent Diffusion Transformer for Video Generation](https://huggingface.co/papers/2401.03048) from Monash University, Shanghai AI Lab, Nanjing University, and Nanyang Technological University. + +The abstract from the paper is: + +*We propose a novel Latent Diffusion Transformer, namely Latte, for video generation. Latte first extracts spatio-temporal tokens from input videos and then adopts a series of Transformer blocks to model video distribution in the latent space. In order to model a substantial number of tokens extracted from videos, four efficient variants are introduced from the perspective of decomposing the spatial and temporal dimensions of input videos. To improve the quality of generated videos, we determine the best practices of Latte through rigorous experimental analysis, including video clip patch embedding, model variants, timestep-class information injection, temporal positional embedding, and learning strategies. Our comprehensive evaluation demonstrates that Latte achieves state-of-the-art performance across four standard video generation datasets, i.e., FaceForensics, SkyTimelapse, UCF101, and Taichi-HD. In addition, we extend Latte to text-to-video generation (T2V) task, where Latte achieves comparable results compared to recent T2V models. We strongly believe that Latte provides valuable insights for future research on incorporating Transformers into diffusion models for video generation.* + +**Highlights**: Latte is a latent diffusion transformer proposed as a backbone for modeling different modalities (trained for text-to-video generation here). It achieves state-of-the-art performance across four standard video benchmarks - [FaceForensics](https://huggingface.co/papers/1803.09179), [SkyTimelapse](https://huggingface.co/papers/1709.07592), [UCF101](https://huggingface.co/papers/1212.0402) and [Taichi-HD](https://huggingface.co/papers/2003.00196). To prepare and download the datasets for evaluation, please refer to [this https URL](https://github.com/Vchitect/Latte/blob/main/docs/datasets_evaluation.md). + +This pipeline was contributed by [maxin-cn](https://github.com/maxin-cn). The original codebase can be found [here](https://github.com/Vchitect/Latte). The original weights can be found under [hf.co/maxin-cn](https://huggingface.co/maxin-cn). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +### Inference + +Use [`torch.compile`](https://huggingface.co/docs/diffusers/main/en/tutorials/fast_diffusion#torchcompile) to reduce the inference latency. + +First, load the pipeline: + +```python +import torch +from diffusers import LattePipeline + +pipeline = LattePipeline.from_pretrained( + "maxin-cn/Latte-1", torch_dtype=torch.float16 +).to("cuda") +``` + +Then change the memory layout of the pipelines `transformer` and `vae` components to `torch.channels-last`: + +```python +pipeline.transformer.to(memory_format=torch.channels_last) +pipeline.vae.to(memory_format=torch.channels_last) +``` + +Finally, compile the components and run inference: + +```python +pipeline.transformer = torch.compile(pipeline.transformer) +pipeline.vae.decode = torch.compile(pipeline.vae.decode) + +video = pipeline(prompt="A dog wearing sunglasses floating in space, surreal, nebulae in background").frames[0] +``` + +The [benchmark](https://gist.github.com/a-r-r-o-w/4e1694ca46374793c0361d740a99ff19) results on an 80GB A100 machine are: + +``` +Without torch.compile(): Average inference time: 16.246 seconds. +With torch.compile(): Average inference time: 14.573 seconds. +``` + +## Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`LattePipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, LatteTransformer3DModel, LattePipeline +from diffusers.utils import export_to_gif +from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel + +quant_config = BitsAndBytesConfig(load_in_8bit=True) +text_encoder_8bit = T5EncoderModel.from_pretrained( + "maxin-cn/Latte-1", + subfolder="text_encoder", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = LatteTransformer3DModel.from_pretrained( + "maxin-cn/Latte-1", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +pipeline = LattePipeline.from_pretrained( + "maxin-cn/Latte-1", + text_encoder=text_encoder_8bit, + transformer=transformer_8bit, + torch_dtype=torch.float16, + device_map="balanced", +) + +prompt = "A small cactus with a happy face in the Sahara desert." +video = pipeline(prompt).frames[0] +export_to_gif(video, "latte.gif") +``` + +## LattePipeline + +[[autodoc]] LattePipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/ledits_pp.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/ledits_pp.md new file mode 100644 index 0000000000000000000000000000000000000000..7c08971aa8d93511748e81c6f02ed30c060113af --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/ledits_pp.md @@ -0,0 +1,58 @@ + + +# LEDITS++ + +
+ LoRA +
+ +LEDITS++ was proposed in [LEDITS++: Limitless Image Editing using Text-to-Image Models](https://huggingface.co/papers/2311.16711) by Manuel Brack, Felix Friedrich, Katharina Kornmeier, Linoy Tsaban, Patrick Schramowski, Kristian Kersting, Apolinário Passos. + +The abstract from the paper is: + +*Text-to-image diffusion models have recently received increasing interest for their astonishing ability to produce high-fidelity images from solely text inputs. Subsequent research efforts aim to exploit and apply their capabilities to real image editing. However, existing image-to-image methods are often inefficient, imprecise, and of limited versatility. They either require time-consuming fine-tuning, deviate unnecessarily strongly from the input image, and/or lack support for multiple, simultaneous edits. To address these issues, we introduce LEDITS++, an efficient yet versatile and precise textual image manipulation technique. LEDITS++'s novel inversion approach requires no tuning nor optimization and produces high-fidelity results with a few diffusion steps. Second, our methodology supports multiple simultaneous edits and is architecture-agnostic. Third, we use a novel implicit masking technique that limits changes to relevant image regions. We propose the novel TEdBench++ benchmark as part of our exhaustive evaluation. Our results demonstrate the capabilities of LEDITS++ and its improvements over previous methods. The project page is available at https://leditsplusplus-project.static.hf.space .* + + + +You can find additional information about LEDITS++ on the [project page](https://leditsplusplus-project.static.hf.space/index.html) and try it out in a [demo](https://huggingface.co/spaces/editing-images/leditsplusplus). + + + + +Due to some backward compatibility issues with the current diffusers implementation of [`~schedulers.DPMSolverMultistepScheduler`] this implementation of LEdits++ can no longer guarantee perfect inversion. +This issue is unlikely to have any noticeable effects on applied use-cases. However, we provide an alternative implementation that guarantees perfect inversion in a dedicated [GitHub repo](https://github.com/ml-research/ledits_pp). + + +We provide two distinct pipelines based on different pre-trained models. + +## LEditsPPPipelineStableDiffusion +[[autodoc]] pipelines.ledits_pp.LEditsPPPipelineStableDiffusion + - all + - __call__ + - invert + +## LEditsPPPipelineStableDiffusionXL +[[autodoc]] pipelines.ledits_pp.LEditsPPPipelineStableDiffusionXL + - all + - __call__ + - invert + + + +## LEditsPPDiffusionPipelineOutput +[[autodoc]] pipelines.ledits_pp.pipeline_output.LEditsPPDiffusionPipelineOutput + - all + +## LEditsPPInversionPipelineOutput +[[autodoc]] pipelines.ledits_pp.pipeline_output.LEditsPPInversionPipelineOutput + - all diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/ltx_video.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/ltx_video.md new file mode 100644 index 0000000000000000000000000000000000000000..0ad558fef9d728401e89bd065e3ddabd3db93498 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/ltx_video.md @@ -0,0 +1,412 @@ + + +# LTX Video + +
+ LoRA + MPS +
+ +[LTX Video](https://huggingface.co/Lightricks/LTX-Video) is the first DiT-based video generation model capable of generating high-quality videos in real-time. It produces 24 FPS videos at a 768x512 resolution faster than they can be watched. Trained on a large-scale dataset of diverse videos, the model generates high-resolution videos with realistic and varied content. We provide a model for both text-to-video as well as image + text-to-video usecases. + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +Available models: + +| Model name | Recommended dtype | +|:-------------:|:-----------------:| +| [`LTX Video 2B 0.9.0`](https://huggingface.co/Lightricks/LTX-Video/blob/main/ltx-video-2b-v0.9.safetensors) | `torch.bfloat16` | +| [`LTX Video 2B 0.9.1`](https://huggingface.co/Lightricks/LTX-Video/blob/main/ltx-video-2b-v0.9.1.safetensors) | `torch.bfloat16` | +| [`LTX Video 2B 0.9.5`](https://huggingface.co/Lightricks/LTX-Video/blob/main/ltx-video-2b-v0.9.5.safetensors) | `torch.bfloat16` | +| [`LTX Video 13B 0.9.7`](https://huggingface.co/Lightricks/LTX-Video/blob/main/ltxv-13b-0.9.7-dev.safetensors) | `torch.bfloat16` | +| [`LTX Video 13B 0.9.7 (distilled)`](https://huggingface.co/Lightricks/LTX-Video/blob/main/ltxv-13b-0.9.7-distilled.safetensors) | `torch.bfloat16` | +| [`LTX Video Spatial Upscaler 0.9.7`](https://huggingface.co/Lightricks/LTX-Video/blob/main/ltxv-spatial-upscaler-0.9.7.safetensors) | `torch.bfloat16` | + +Note: The recommended dtype is for the transformer component. The VAE and text encoders can be either `torch.float32`, `torch.bfloat16` or `torch.float16` but the recommended dtype is `torch.bfloat16` as used in the original repository. + +## Recommended settings for generation + +For the best results, it is recommended to follow the guidelines mentioned in the official LTX Video [repository](https://github.com/Lightricks/LTX-Video). + +- Some variants of LTX Video are guidance-distilled. For guidance-distilled models, `guidance_scale` must be set to `1.0`. For any other models, `guidance_scale` should be set higher (e.g., `5.0`) for good generation quality. +- For variants with a timestep-aware VAE (LTXV 0.9.1 and above), it is recommended to set `decode_timestep` to `0.05` and `image_cond_noise_scale` to `0.025`. +- For variants that support interpolation between multiple conditioning images and videos (LTXV 0.9.5 and above), it is recommended to use similar looking images/videos for the best results. High divergence between the conditionings may lead to abrupt transitions in the generated video. + + + + + +The examples below show some recommended generation settings, but note that all features supported in the original [LTX Video repository](https://github.com/Lightricks/LTX-Video) are not supported in `diffusers` yet (for example, Spatio-temporal Guidance and CRF compression for image inputs). This will gradually be supported in the future. For the best possible generation quality, we recommend using the code from the original repository. + + + +## Using LTX Video 13B 0.9.7 + +LTX Video 0.9.7 comes with a spatial latent upscaler and a 13B parameter transformer. The inference involves generating a low resolution video first, which is very fast, followed by upscaling and refining the generated video. + + + +```python +import torch +from diffusers import LTXConditionPipeline, LTXLatentUpsamplePipeline +from diffusers.pipelines.ltx.pipeline_ltx_condition import LTXVideoCondition +from diffusers.utils import export_to_video, load_video + +pipe = LTXConditionPipeline.from_pretrained("Lightricks/LTX-Video-0.9.7-dev", torch_dtype=torch.bfloat16) +pipe_upsample = LTXLatentUpsamplePipeline.from_pretrained("Lightricks/ltxv-spatial-upscaler-0.9.7", vae=pipe.vae, torch_dtype=torch.bfloat16) +pipe.to("cuda") +pipe_upsample.to("cuda") +pipe.vae.enable_tiling() + +def round_to_nearest_resolution_acceptable_by_vae(height, width): + height = height - (height % pipe.vae_temporal_compression_ratio) + width = width - (width % pipe.vae_temporal_compression_ratio) + return height, width + +video = load_video( + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/cosmos/cosmos-video2world-input-vid.mp4" +)[:21] # Use only the first 21 frames as conditioning +condition1 = LTXVideoCondition(video=video, frame_index=0) + +prompt = "The video depicts a winding mountain road covered in snow, with a single vehicle traveling along it. The road is flanked by steep, rocky cliffs and sparse vegetation. The landscape is characterized by rugged terrain and a river visible in the distance. The scene captures the solitude and beauty of a winter drive through a mountainous region." +negative_prompt = "worst quality, inconsistent motion, blurry, jittery, distorted" +expected_height, expected_width = 768, 1152 +downscale_factor = 2 / 3 +num_frames = 161 + +# Part 1. Generate video at smaller resolution +# Text-only conditioning is also supported without the need to pass `conditions` +downscaled_height, downscaled_width = int(expected_height * downscale_factor), int(expected_width * downscale_factor) +downscaled_height, downscaled_width = round_to_nearest_resolution_acceptable_by_vae(downscaled_height, downscaled_width) +latents = pipe( + conditions=[condition1], + prompt=prompt, + negative_prompt=negative_prompt, + width=downscaled_width, + height=downscaled_height, + num_frames=num_frames, + num_inference_steps=30, + decode_timestep=0.05, + decode_noise_scale=0.025, + image_cond_noise_scale=0.0, + guidance_scale=5.0, + guidance_rescale=0.7, + generator=torch.Generator().manual_seed(0), + output_type="latent", +).frames + +# Part 2. Upscale generated video using latent upsampler with fewer inference steps +# The available latent upsampler upscales the height/width by 2x +upscaled_height, upscaled_width = downscaled_height * 2, downscaled_width * 2 +upscaled_latents = pipe_upsample( + latents=latents, + output_type="latent" +).frames + +# Part 3. Denoise the upscaled video with few steps to improve texture (optional, but recommended) +video = pipe( + conditions=[condition1], + prompt=prompt, + negative_prompt=negative_prompt, + width=upscaled_width, + height=upscaled_height, + num_frames=num_frames, + denoise_strength=0.4, # Effectively, 4 inference steps out of 10 + num_inference_steps=10, + latents=upscaled_latents, + decode_timestep=0.05, + decode_noise_scale=0.025, + image_cond_noise_scale=0.0, + guidance_scale=5.0, + guidance_rescale=0.7, + generator=torch.Generator().manual_seed(0), + output_type="pil", +).frames[0] + +# Part 4. Downscale the video to the expected resolution +video = [frame.resize((expected_width, expected_height)) for frame in video] + +export_to_video(video, "output.mp4", fps=24) +``` + +## Using LTX Video 0.9.7 (distilled) + +The same example as above can be used with the exception of the `guidance_scale` parameter. The model is both guidance and timestep distilled in order to speedup generation. It requires `guidance_scale` to be set to `1.0`. Additionally, to benefit from the timestep distillation, `num_inference_steps` can be set between `4` and `10` for good generation quality. + +Additionally, custom timesteps can also be used for conditioning the generation. The authors recommend using the following timesteps for best results: +- Base model inference to prepare for upscaling: `[1000, 993, 987, 981, 975, 909, 725, 0.03]` +- Upscaling: `[1000, 909, 725, 421, 0]` + +
+ Full example + +```python +import torch +from diffusers import LTXConditionPipeline, LTXLatentUpsamplePipeline +from diffusers.pipelines.ltx.pipeline_ltx_condition import LTXVideoCondition +from diffusers.utils import export_to_video, load_video + +pipe = LTXConditionPipeline.from_pretrained("Lightricks/LTX-Video-0.9.7-distilled", torch_dtype=torch.bfloat16) +pipe_upsample = LTXLatentUpsamplePipeline.from_pretrained("Lightricks/ltxv-spatial-upscaler-0.9.7", vae=pipe.vae, torch_dtype=torch.bfloat16) +pipe.to("cuda") +pipe_upsample.to("cuda") +pipe.vae.enable_tiling() + +def round_to_nearest_resolution_acceptable_by_vae(height, width): + height = height - (height % pipe.vae_temporal_compression_ratio) + width = width - (width % pipe.vae_temporal_compression_ratio) + return height, width + +prompt = "artistic anatomical 3d render, utlra quality, human half full male body with transparent skin revealing structure instead of organs, muscular, intricate creative patterns, monochromatic with backlighting, lightning mesh, scientific concept art, blending biology with botany, surreal and ethereal quality, unreal engine 5, ray tracing, ultra realistic, 16K UHD, rich details. camera zooms out in a rotating fashion" +negative_prompt = "worst quality, inconsistent motion, blurry, jittery, distorted" +expected_height, expected_width = 768, 1152 +downscale_factor = 2 / 3 +num_frames = 161 + +# Part 1. Generate video at smaller resolution +downscaled_height, downscaled_width = int(expected_height * downscale_factor), int(expected_width * downscale_factor) +downscaled_height, downscaled_width = round_to_nearest_resolution_acceptable_by_vae(downscaled_height, downscaled_width) +latents = pipe( + prompt=prompt, + negative_prompt=negative_prompt, + width=downscaled_width, + height=downscaled_height, + num_frames=num_frames, + timesteps=[1000, 993, 987, 981, 975, 909, 725, 0.03], + decode_timestep=0.05, + decode_noise_scale=0.025, + image_cond_noise_scale=0.0, + guidance_scale=1.0, + guidance_rescale=0.7, + generator=torch.Generator().manual_seed(0), + output_type="latent", +).frames + +# Part 2. Upscale generated video using latent upsampler with fewer inference steps +# The available latent upsampler upscales the height/width by 2x +upscaled_height, upscaled_width = downscaled_height * 2, downscaled_width * 2 +upscaled_latents = pipe_upsample( + latents=latents, + adain_factor=1.0, + output_type="latent" +).frames + +# Part 3. Denoise the upscaled video with few steps to improve texture (optional, but recommended) +video = pipe( + prompt=prompt, + negative_prompt=negative_prompt, + width=upscaled_width, + height=upscaled_height, + num_frames=num_frames, + denoise_strength=0.999, # Effectively, 4 inference steps out of 5 + timesteps=[1000, 909, 725, 421, 0], + latents=upscaled_latents, + decode_timestep=0.05, + decode_noise_scale=0.025, + image_cond_noise_scale=0.0, + guidance_scale=1.0, + guidance_rescale=0.7, + generator=torch.Generator().manual_seed(0), + output_type="pil", +).frames[0] + +# Part 4. Downscale the video to the expected resolution +video = [frame.resize((expected_width, expected_height)) for frame in video] + +export_to_video(video, "output.mp4", fps=24) +``` + +
+ +## Loading Single Files + +Loading the original LTX Video checkpoints is also possible with [`~ModelMixin.from_single_file`]. We recommend using `from_single_file` for the Lightricks series of models, as they plan to release multiple models in the future in the single file format. + +```python +import torch +from diffusers import AutoencoderKLLTXVideo, LTXImageToVideoPipeline, LTXVideoTransformer3DModel + +# `single_file_url` could also be https://huggingface.co/Lightricks/LTX-Video/ltx-video-2b-v0.9.1.safetensors +single_file_url = "https://huggingface.co/Lightricks/LTX-Video/ltx-video-2b-v0.9.safetensors" +transformer = LTXVideoTransformer3DModel.from_single_file( + single_file_url, torch_dtype=torch.bfloat16 +) +vae = AutoencoderKLLTXVideo.from_single_file(single_file_url, torch_dtype=torch.bfloat16) +pipe = LTXImageToVideoPipeline.from_pretrained( + "Lightricks/LTX-Video", transformer=transformer, vae=vae, torch_dtype=torch.bfloat16 +) + +# ... inference code ... +``` + +Alternatively, the pipeline can be used to load the weights with [`~FromSingleFileMixin.from_single_file`]. + +```python +import torch +from diffusers import LTXImageToVideoPipeline +from transformers import T5EncoderModel, T5Tokenizer + +single_file_url = "https://huggingface.co/Lightricks/LTX-Video/ltx-video-2b-v0.9.safetensors" +text_encoder = T5EncoderModel.from_pretrained( + "Lightricks/LTX-Video", subfolder="text_encoder", torch_dtype=torch.bfloat16 +) +tokenizer = T5Tokenizer.from_pretrained( + "Lightricks/LTX-Video", subfolder="tokenizer", torch_dtype=torch.bfloat16 +) +pipe = LTXImageToVideoPipeline.from_single_file( + single_file_url, text_encoder=text_encoder, tokenizer=tokenizer, torch_dtype=torch.bfloat16 +) +``` + +Loading [LTX GGUF checkpoints](https://huggingface.co/city96/LTX-Video-gguf) are also supported: + +```py +import torch +from diffusers.utils import export_to_video +from diffusers import LTXPipeline, LTXVideoTransformer3DModel, GGUFQuantizationConfig + +ckpt_path = ( + "https://huggingface.co/city96/LTX-Video-gguf/blob/main/ltx-video-2b-v0.9-Q3_K_S.gguf" +) +transformer = LTXVideoTransformer3DModel.from_single_file( + ckpt_path, + quantization_config=GGUFQuantizationConfig(compute_dtype=torch.bfloat16), + torch_dtype=torch.bfloat16, +) +pipe = LTXPipeline.from_pretrained( + "Lightricks/LTX-Video", + transformer=transformer, + torch_dtype=torch.bfloat16, +) +pipe.enable_model_cpu_offload() + +prompt = "A woman with long brown hair and light skin smiles at another woman with long blonde hair. The woman with brown hair wears a black jacket and has a small, barely noticeable mole on her right cheek. The camera angle is a close-up, focused on the woman with brown hair's face. The lighting is warm and natural, likely from the setting sun, casting a soft glow on the scene. The scene appears to be real-life footage" +negative_prompt = "worst quality, inconsistent motion, blurry, jittery, distorted" + +video = pipe( + prompt=prompt, + negative_prompt=negative_prompt, + width=704, + height=480, + num_frames=161, + num_inference_steps=50, +).frames[0] +export_to_video(video, "output_gguf_ltx.mp4", fps=24) +``` + +Make sure to read the [documentation on GGUF](../../quantization/gguf) to learn more about our GGUF support. + + + +Loading and running inference with [LTX Video 0.9.1](https://huggingface.co/Lightricks/LTX-Video/blob/main/ltx-video-2b-v0.9.1.safetensors) weights. + +```python +import torch +from diffusers import LTXPipeline +from diffusers.utils import export_to_video + +pipe = LTXPipeline.from_pretrained("a-r-r-o-w/LTX-Video-0.9.1-diffusers", torch_dtype=torch.bfloat16) +pipe.to("cuda") + +prompt = "A woman with long brown hair and light skin smiles at another woman with long blonde hair. The woman with brown hair wears a black jacket and has a small, barely noticeable mole on her right cheek. The camera angle is a close-up, focused on the woman with brown hair's face. The lighting is warm and natural, likely from the setting sun, casting a soft glow on the scene. The scene appears to be real-life footage" +negative_prompt = "worst quality, inconsistent motion, blurry, jittery, distorted" + +video = pipe( + prompt=prompt, + negative_prompt=negative_prompt, + width=768, + height=512, + num_frames=161, + decode_timestep=0.03, + decode_noise_scale=0.025, + num_inference_steps=50, +).frames[0] +export_to_video(video, "output.mp4", fps=24) +``` + +Refer to [this section](https://huggingface.co/docs/diffusers/main/en/api/pipelines/cogvideox#memory-optimization) to learn more about optimizing memory consumption. + +## Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`LTXPipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, LTXVideoTransformer3DModel, LTXPipeline +from diffusers.utils import export_to_video +from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel + +quant_config = BitsAndBytesConfig(load_in_8bit=True) +text_encoder_8bit = T5EncoderModel.from_pretrained( + "Lightricks/LTX-Video", + subfolder="text_encoder", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = LTXVideoTransformer3DModel.from_pretrained( + "Lightricks/LTX-Video", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +pipeline = LTXPipeline.from_pretrained( + "Lightricks/LTX-Video", + text_encoder=text_encoder_8bit, + transformer=transformer_8bit, + torch_dtype=torch.float16, + device_map="balanced", +) + +prompt = "A detailed wooden toy ship with intricately carved masts and sails is seen gliding smoothly over a plush, blue carpet that mimics the waves of the sea. The ship's hull is painted a rich brown, with tiny windows. The carpet, soft and textured, provides a perfect backdrop, resembling an oceanic expanse. Surrounding the ship are various other toys and children's items, hinting at a playful environment. The scene captures the innocence and imagination of childhood, with the toy ship's journey symbolizing endless adventures in a whimsical, indoor setting." +video = pipeline(prompt=prompt, num_frames=161, num_inference_steps=50).frames[0] +export_to_video(video, "ship.mp4", fps=24) +``` + +## LTXPipeline + +[[autodoc]] LTXPipeline + - all + - __call__ + +## LTXImageToVideoPipeline + +[[autodoc]] LTXImageToVideoPipeline + - all + - __call__ + +## LTXConditionPipeline + +[[autodoc]] LTXConditionPipeline + - all + - __call__ + +## LTXLatentUpsamplePipeline + +[[autodoc]] LTXLatentUpsamplePipeline + - all + - __call__ + +## LTXPipelineOutput + +[[autodoc]] pipelines.ltx.pipeline_output.LTXPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/lumina.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/lumina.md new file mode 100644 index 0000000000000000000000000000000000000000..9e5e847bd415ee39db18f7da75ad43bb38725f40 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/lumina.md @@ -0,0 +1,130 @@ + + +# Lumina-T2X +![concepts](https://github.com/Alpha-VLLM/Lumina-T2X/assets/54879512/9f52eabb-07dc-4881-8257-6d8a5f2a0a5a) + +[Lumina-Next : Making Lumina-T2X Stronger and Faster with Next-DiT](https://github.com/Alpha-VLLM/Lumina-T2X/blob/main/assets/lumina-next.pdf) from Alpha-VLLM, OpenGVLab, Shanghai AI Laboratory. + +The abstract from the paper is: + +*Lumina-T2X is a nascent family of Flow-based Large Diffusion Transformers (Flag-DiT) that establishes a unified framework for transforming noise into various modalities, such as images and videos, conditioned on text instructions. Despite its promising capabilities, Lumina-T2X still encounters challenges including training instability, slow inference, and extrapolation artifacts. In this paper, we present Lumina-Next, an improved version of Lumina-T2X, showcasing stronger generation performance with increased training and inference efficiency. We begin with a comprehensive analysis of the Flag-DiT architecture and identify several suboptimal components, which we address by introducing the Next-DiT architecture with 3D RoPE and sandwich normalizations. To enable better resolution extrapolation, we thoroughly compare different context extrapolation methods applied to text-to-image generation with 3D RoPE, and propose Frequency- and Time-Aware Scaled RoPE tailored for diffusion transformers. Additionally, we introduce a sigmoid time discretization schedule to reduce sampling steps in solving the Flow ODE and the Context Drop method to merge redundant visual tokens for faster network evaluation, effectively boosting the overall sampling speed. Thanks to these improvements, Lumina-Next not only improves the quality and efficiency of basic text-to-image generation but also demonstrates superior resolution extrapolation capabilities and multilingual generation using decoder-based LLMs as the text encoder, all in a zero-shot manner. To further validate Lumina-Next as a versatile generative framework, we instantiate it on diverse tasks including visual recognition, multi-view, audio, music, and point cloud generation, showcasing strong performance across these domains. By releasing all codes and model weights at https://github.com/Alpha-VLLM/Lumina-T2X, we aim to advance the development of next-generation generative AI capable of universal modeling.* + +**Highlights**: Lumina-Next is a next-generation Diffusion Transformer that significantly enhances text-to-image generation, multilingual generation, and multitask performance by introducing the Next-DiT architecture, 3D RoPE, and frequency- and time-aware RoPE, among other improvements. + +Lumina-Next has the following components: +* It improves sampling efficiency with fewer and faster Steps. +* It uses a Next-DiT as a transformer backbone with Sandwichnorm 3D RoPE, and Grouped-Query Attention. +* It uses a Frequency- and Time-Aware Scaled RoPE. + +--- + +[Lumina-T2X: Transforming Text into Any Modality, Resolution, and Duration via Flow-based Large Diffusion Transformers](https://huggingface.co/papers/2405.05945) from Alpha-VLLM, OpenGVLab, Shanghai AI Laboratory. + +The abstract from the paper is: + +*Sora unveils the potential of scaling Diffusion Transformer for generating photorealistic images and videos at arbitrary resolutions, aspect ratios, and durations, yet it still lacks sufficient implementation details. In this technical report, we introduce the Lumina-T2X family - a series of Flow-based Large Diffusion Transformers (Flag-DiT) equipped with zero-initialized attention, as a unified framework designed to transform noise into images, videos, multi-view 3D objects, and audio clips conditioned on text instructions. By tokenizing the latent spatial-temporal space and incorporating learnable placeholders such as [nextline] and [nextframe] tokens, Lumina-T2X seamlessly unifies the representations of different modalities across various spatial-temporal resolutions. This unified approach enables training within a single framework for different modalities and allows for flexible generation of multimodal data at any resolution, aspect ratio, and length during inference. Advanced techniques like RoPE, RMSNorm, and flow matching enhance the stability, flexibility, and scalability of Flag-DiT, enabling models of Lumina-T2X to scale up to 7 billion parameters and extend the context window to 128K tokens. This is particularly beneficial for creating ultra-high-definition images with our Lumina-T2I model and long 720p videos with our Lumina-T2V model. Remarkably, Lumina-T2I, powered by a 5-billion-parameter Flag-DiT, requires only 35% of the training computational costs of a 600-million-parameter naive DiT. Our further comprehensive analysis underscores Lumina-T2X's preliminary capability in resolution extrapolation, high-resolution editing, generating consistent 3D views, and synthesizing videos with seamless transitions. We expect that the open-sourcing of Lumina-T2X will further foster creativity, transparency, and diversity in the generative AI community.* + + +You can find the original codebase at [Alpha-VLLM](https://github.com/Alpha-VLLM/Lumina-T2X) and all the available checkpoints at [Alpha-VLLM Lumina Family](https://huggingface.co/collections/Alpha-VLLM/lumina-family-66423205bedb81171fd0644b). + +**Highlights**: Lumina-T2X supports Any Modality, Resolution, and Duration. + +Lumina-T2X has the following components: +* It uses a Flow-based Large Diffusion Transformer as the backbone +* It supports different any modalities with one backbone and corresponding encoder, decoder. + +This pipeline was contributed by [PommesPeter](https://github.com/PommesPeter). The original codebase can be found [here](https://github.com/Alpha-VLLM/Lumina-T2X). The original weights can be found under [hf.co/Alpha-VLLM](https://huggingface.co/Alpha-VLLM). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +### Inference (Text-to-Image) + +Use [`torch.compile`](https://huggingface.co/docs/diffusers/main/en/tutorials/fast_diffusion#torchcompile) to reduce the inference latency. + +First, load the pipeline: + +```python +from diffusers import LuminaPipeline +import torch + +pipeline = LuminaPipeline.from_pretrained( + "Alpha-VLLM/Lumina-Next-SFT-diffusers", torch_dtype=torch.bfloat16 +).to("cuda") +``` + +Then change the memory layout of the pipelines `transformer` and `vae` components to `torch.channels-last`: + +```python +pipeline.transformer.to(memory_format=torch.channels_last) +pipeline.vae.to(memory_format=torch.channels_last) +``` + +Finally, compile the components and run inference: + +```python +pipeline.transformer = torch.compile(pipeline.transformer, mode="max-autotune", fullgraph=True) +pipeline.vae.decode = torch.compile(pipeline.vae.decode, mode="max-autotune", fullgraph=True) + +image = pipeline(prompt="Upper body of a young woman in a Victorian-era outfit with brass goggles and leather straps. Background shows an industrial revolution cityscape with smoky skies and tall, metal structures").images[0] +``` + +## Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`LuminaPipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, Transformer2DModel, LuminaPipeline +from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel + +quant_config = BitsAndBytesConfig(load_in_8bit=True) +text_encoder_8bit = T5EncoderModel.from_pretrained( + "Alpha-VLLM/Lumina-Next-SFT-diffusers", + subfolder="text_encoder", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = Transformer2DModel.from_pretrained( + "Alpha-VLLM/Lumina-Next-SFT-diffusers", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +pipeline = LuminaPipeline.from_pretrained( + "Alpha-VLLM/Lumina-Next-SFT-diffusers", + text_encoder=text_encoder_8bit, + transformer=transformer_8bit, + torch_dtype=torch.float16, + device_map="balanced", +) + +prompt = "a tiny astronaut hatching from an egg on the moon" +image = pipeline(prompt).images[0] +image.save("lumina.png") +``` + +## LuminaPipeline + +[[autodoc]] LuminaPipeline + - all + - __call__ + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/lumina2.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/lumina2.md new file mode 100644 index 0000000000000000000000000000000000000000..57f0e8e2105d042e3ae27a8b3513e6db8f994d0e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/lumina2.md @@ -0,0 +1,87 @@ + + +# Lumina2 + +
+ LoRA +
+ +[Lumina Image 2.0: A Unified and Efficient Image Generative Model](https://huggingface.co/Alpha-VLLM/Lumina-Image-2.0) is a 2 billion parameter flow-based diffusion transformer capable of generating diverse images from text descriptions. + +The abstract from the paper is: + +*We introduce Lumina-Image 2.0, an advanced text-to-image model that surpasses previous state-of-the-art methods across multiple benchmarks, while also shedding light on its potential to evolve into a generalist vision intelligence model. Lumina-Image 2.0 exhibits three key properties: (1) Unification – it adopts a unified architecture that treats text and image tokens as a joint sequence, enabling natural cross-modal interactions and facilitating task expansion. Besides, since high-quality captioners can provide semantically better-aligned text-image training pairs, we introduce a unified captioning system, UniCaptioner, which generates comprehensive and precise captions for the model. This not only accelerates model convergence but also enhances prompt adherence, variable-length prompt handling, and task generalization via prompt templates. (2) Efficiency – to improve the efficiency of the unified architecture, we develop a set of optimization techniques that improve semantic learning and fine-grained texture generation during training while incorporating inference-time acceleration strategies without compromising image quality. (3) Transparency – we open-source all training details, code, and models to ensure full reproducibility, aiming to bridge the gap between well-resourced closed-source research teams and independent developers.* + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## Using Single File loading with Lumina Image 2.0 + +Single file loading for Lumina Image 2.0 is available for the `Lumina2Transformer2DModel` + +```python +import torch +from diffusers import Lumina2Transformer2DModel, Lumina2Pipeline + +ckpt_path = "https://huggingface.co/Alpha-VLLM/Lumina-Image-2.0/blob/main/consolidated.00-of-01.pth" +transformer = Lumina2Transformer2DModel.from_single_file( + ckpt_path, torch_dtype=torch.bfloat16 +) + +pipe = Lumina2Pipeline.from_pretrained( + "Alpha-VLLM/Lumina-Image-2.0", transformer=transformer, torch_dtype=torch.bfloat16 +) +pipe.enable_model_cpu_offload() +image = pipe( + "a cat holding a sign that says hello", + generator=torch.Generator("cpu").manual_seed(0), +).images[0] +image.save("lumina-single-file.png") + +``` + +## Using GGUF Quantized Checkpoints with Lumina Image 2.0 + +GGUF Quantized checkpoints for the `Lumina2Transformer2DModel` can be loaded via `from_single_file` with the `GGUFQuantizationConfig` + +```python +from diffusers import Lumina2Transformer2DModel, Lumina2Pipeline, GGUFQuantizationConfig + +ckpt_path = "https://huggingface.co/calcuis/lumina-gguf/blob/main/lumina2-q4_0.gguf" +transformer = Lumina2Transformer2DModel.from_single_file( + ckpt_path, + quantization_config=GGUFQuantizationConfig(compute_dtype=torch.bfloat16), + torch_dtype=torch.bfloat16, +) + +pipe = Lumina2Pipeline.from_pretrained( + "Alpha-VLLM/Lumina-Image-2.0", transformer=transformer, torch_dtype=torch.bfloat16 +) +pipe.enable_model_cpu_offload() +image = pipe( + "a cat holding a sign that says hello", + generator=torch.Generator("cpu").manual_seed(0), +).images[0] +image.save("lumina-gguf.png") +``` + +## Lumina2Pipeline + +[[autodoc]] Lumina2Pipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/marigold.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/marigold.md new file mode 100644 index 0000000000000000000000000000000000000000..e9ca0df067bac39621c886ee43c329bd90d422f9 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/marigold.md @@ -0,0 +1,131 @@ + + +# Marigold Computer Vision + +![marigold](https://marigoldmonodepth.github.io/images/teaser_collage_compressed.jpg) + +Marigold was proposed in +[Repurposing Diffusion-Based Image Generators for Monocular Depth Estimation](https://huggingface.co/papers/2312.02145), +a CVPR 2024 Oral paper by +[Bingxin Ke](http://www.kebingxin.com/), +[Anton Obukhov](https://www.obukhov.ai/), +[Shengyu Huang](https://shengyuh.github.io/), +[Nando Metzger](https://nandometzger.github.io/), +[Rodrigo Caye Daudt](https://rcdaudt.github.io/), and +[Konrad Schindler](https://scholar.google.com/citations?user=FZuNgqIAAAAJ&hl=en). +The core idea is to **repurpose the generative prior of Text-to-Image Latent Diffusion Models (LDMs) for traditional +computer vision tasks**. +This approach was explored by fine-tuning Stable Diffusion for **Monocular Depth Estimation**, as demonstrated in the +teaser above. + +Marigold was later extended in the follow-up paper, +[Marigold: Affordable Adaptation of Diffusion-Based Image Generators for Image Analysis](https://huggingface.co/papers/2312.02145), +authored by +[Bingxin Ke](http://www.kebingxin.com/), +[Kevin Qu](https://www.linkedin.com/in/kevin-qu-b3417621b/?locale=en_US), +[Tianfu Wang](https://tianfwang.github.io/), +[Nando Metzger](https://nandometzger.github.io/), +[Shengyu Huang](https://shengyuh.github.io/), +[Bo Li](https://www.linkedin.com/in/bobboli0202/), +[Anton Obukhov](https://www.obukhov.ai/), and +[Konrad Schindler](https://scholar.google.com/citations?user=FZuNgqIAAAAJ&hl=en). +This work expanded Marigold to support new modalities such as **Surface Normals** and **Intrinsic Image Decomposition** +(IID), introduced a training protocol for **Latent Consistency Models** (LCM), and demonstrated **High-Resolution** (HR) +processing capability. + + + +The early Marigold models (`v1-0` and earlier) were optimized for best results with at least 10 inference steps. +LCM models were later developed to enable high-quality inference in just 1 to 4 steps. +Marigold models `v1-1` and later use the DDIM scheduler to achieve optimal +results in as few as 1 to 4 steps. + + + +## Available Pipelines + +Each pipeline is tailored for a specific computer vision task, processing an input RGB image and generating a +corresponding prediction. +Currently, the following computer vision tasks are implemented: + +| Pipeline | Recommended Model Checkpoints | Spaces (Interactive Apps) | Predicted Modalities | +|---------------------------------------------------------------------------------------------------------------------------------------------------|---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------|:------------------------------------------------------------------------------------:|------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------| +| [MarigoldDepthPipeline](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/marigold/pipeline_marigold_depth.py) | [prs-eth/marigold-depth-v1-1](https://huggingface.co/prs-eth/marigold-depth-v1-1) | [Depth Estimation](https://huggingface.co/spaces/prs-eth/marigold) | [Depth](https://en.wikipedia.org/wiki/Depth_map), [Disparity](https://en.wikipedia.org/wiki/Binocular_disparity) | +| [MarigoldNormalsPipeline](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/marigold/pipeline_marigold_normals.py) | [prs-eth/marigold-normals-v1-1](https://huggingface.co/prs-eth/marigold-normals-v1-1) | [Surface Normals Estimation](https://huggingface.co/spaces/prs-eth/marigold-normals) | [Surface normals](https://en.wikipedia.org/wiki/Normal_mapping) | +| [MarigoldIntrinsicsPipeline](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/marigold/pipeline_marigold_intrinsics.py) | [prs-eth/marigold-iid-appearance-v1-1](https://huggingface.co/prs-eth/marigold-iid-appearance-v1-1),
[prs-eth/marigold-iid-lighting-v1-1](https://huggingface.co/prs-eth/marigold-iid-lighting-v1-1) | [Intrinsic Image Decomposition](https://huggingface.co/spaces/prs-eth/marigold-iid) | [Albedo](https://en.wikipedia.org/wiki/Albedo), [Materials](https://www.n.aiq3d.com/wiki/roughnessmetalnessao-map), [Lighting](https://en.wikipedia.org/wiki/Diffuse_reflection) | + +## Available Checkpoints + +All original checkpoints are available under the [PRS-ETH](https://huggingface.co/prs-eth/) organization on Hugging Face. +They are designed for use with diffusers pipelines and the [original codebase](https://github.com/prs-eth/marigold), which can also be used to train +new model checkpoints. +The following is a summary of the recommended checkpoints, all of which produce reliable results with 1 to 4 steps. + +| Checkpoint | Modality | Comment | +|-----------------------------------------------------------------------------------------------------|--------------|--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------| +| [prs-eth/marigold-depth-v1-1](https://huggingface.co/prs-eth/marigold-depth-v1-1) | Depth | Affine-invariant depth prediction assigns each pixel a value between 0 (near plane) and 1 (far plane), with both planes determined by the model during inference. | +| [prs-eth/marigold-normals-v0-1](https://huggingface.co/prs-eth/marigold-normals-v0-1) | Normals | The surface normals predictions are unit-length 3D vectors in the screen space camera, with values in the range from -1 to 1. | +| [prs-eth/marigold-iid-appearance-v1-1](https://huggingface.co/prs-eth/marigold-iid-appearance-v1-1) | Intrinsics | InteriorVerse decomposition is comprised of Albedo and two BRDF material properties: Roughness and Metallicity. | +| [prs-eth/marigold-iid-lighting-v1-1](https://huggingface.co/prs-eth/marigold-iid-lighting-v1-1) | Intrinsics | HyperSim decomposition of an image  \\(I\\)  is comprised of Albedo  \\(A\\), Diffuse shading  \\(S\\), and Non-diffuse residual  \\(R\\):  \\(I = A*S+R\\). | + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff +between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to +efficiently load the same components into multiple pipelines. +Also, to know more about reducing the memory usage of this pipeline, refer to the ["Reduce memory usage"] section +[here](../../using-diffusers/svd#reduce-memory-usage). + + + + + +Marigold pipelines were designed and tested with the scheduler embedded in the model checkpoint. +The optimal number of inference steps varies by scheduler, with no universal value that works best across all cases. +To accommodate this, the `num_inference_steps` parameter in the pipeline's `__call__` method defaults to `None` (see the +API reference). +Unless set explicitly, it inherits the value from the `default_denoising_steps` field in the checkpoint configuration +file (`model_index.json`). +This ensures high-quality predictions when invoking the pipeline with only the `image` argument. + + + +See also Marigold [usage examples](../../using-diffusers/marigold_usage). + +## Marigold Depth Prediction API + +[[autodoc]] MarigoldDepthPipeline + - __call__ + +[[autodoc]] pipelines.marigold.pipeline_marigold_depth.MarigoldDepthOutput + +[[autodoc]] pipelines.marigold.marigold_image_processing.MarigoldImageProcessor.visualize_depth + +## Marigold Normals Estimation API +[[autodoc]] MarigoldNormalsPipeline + - __call__ + +[[autodoc]] pipelines.marigold.pipeline_marigold_normals.MarigoldNormalsOutput + +[[autodoc]] pipelines.marigold.marigold_image_processing.MarigoldImageProcessor.visualize_normals + +## Marigold Intrinsic Image Decomposition API + +[[autodoc]] MarigoldIntrinsicsPipeline + - __call__ + +[[autodoc]] pipelines.marigold.pipeline_marigold_intrinsics.MarigoldIntrinsicsOutput + +[[autodoc]] pipelines.marigold.marigold_image_processing.MarigoldImageProcessor.visualize_intrinsics diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/mochi.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/mochi.md new file mode 100644 index 0000000000000000000000000000000000000000..ccbaf40af8f84c8eb12418e833cccd034be4e9e7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/mochi.md @@ -0,0 +1,279 @@ + + +# Mochi 1 Preview + +
+ LoRA +
+ +> [!TIP] +> Only a research preview of the model weights is available at the moment. + +[Mochi 1](https://huggingface.co/genmo/mochi-1-preview) is a video generation model by Genmo with a strong focus on prompt adherence and motion quality. The model features a 10B parameter Asmmetric Diffusion Transformer (AsymmDiT) architecture, and uses non-square QKV and output projection layers to reduce inference memory requirements. A single T5-XXL model is used to encode prompts. + +*Mochi 1 preview is an open state-of-the-art video generation model with high-fidelity motion and strong prompt adherence in preliminary evaluation. This model dramatically closes the gap between closed and open video generation systems. The model is released under a permissive Apache 2.0 license.* + +> [!TIP] +> Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + +## Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`MochiPipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, MochiTransformer3DModel, MochiPipeline +from diffusers.utils import export_to_video +from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel + +quant_config = BitsAndBytesConfig(load_in_8bit=True) +text_encoder_8bit = T5EncoderModel.from_pretrained( + "genmo/mochi-1-preview", + subfolder="text_encoder", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = MochiTransformer3DModel.from_pretrained( + "genmo/mochi-1-preview", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +pipeline = MochiPipeline.from_pretrained( + "genmo/mochi-1-preview", + text_encoder=text_encoder_8bit, + transformer=transformer_8bit, + torch_dtype=torch.float16, + device_map="balanced", +) + +video = pipeline( + "Close-up of a cats eye, with the galaxy reflected in the cats eye. Ultra high resolution 4k.", + num_inference_steps=28, + guidance_scale=3.5 +).frames[0] +export_to_video(video, "cat.mp4") +``` + +## Generating videos with Mochi-1 Preview + +The following example will download the full precision `mochi-1-preview` weights and produce the highest quality results but will require at least 42GB VRAM to run. + +```python +import torch +from diffusers import MochiPipeline +from diffusers.utils import export_to_video + +pipe = MochiPipeline.from_pretrained("genmo/mochi-1-preview") + +# Enable memory savings +pipe.enable_model_cpu_offload() +pipe.enable_vae_tiling() + +prompt = "Close-up of a chameleon's eye, with its scaly skin changing color. Ultra high resolution 4k." + +with torch.autocast("cuda", torch.bfloat16, cache_enabled=False): + frames = pipe(prompt, num_frames=85).frames[0] + +export_to_video(frames, "mochi.mp4", fps=30) +``` + +## Using a lower precision variant to save memory + +The following example will use the `bfloat16` variant of the model and requires 22GB VRAM to run. There is a slight drop in the quality of the generated video as a result. + +```python +import torch +from diffusers import MochiPipeline +from diffusers.utils import export_to_video + +pipe = MochiPipeline.from_pretrained("genmo/mochi-1-preview", variant="bf16", torch_dtype=torch.bfloat16) + +# Enable memory savings +pipe.enable_model_cpu_offload() +pipe.enable_vae_tiling() + +prompt = "Close-up of a chameleon's eye, with its scaly skin changing color. Ultra high resolution 4k." +frames = pipe(prompt, num_frames=85).frames[0] + +export_to_video(frames, "mochi.mp4", fps=30) +``` + +## Reproducing the results from the Genmo Mochi repo + +The [Genmo Mochi implementation](https://github.com/genmoai/mochi/tree/main) uses different precision values for each stage in the inference process. The text encoder and VAE use `torch.float32`, while the DiT uses `torch.bfloat16` with the [attention kernel](https://pytorch.org/docs/stable/generated/torch.nn.attention.sdpa_kernel.html#torch.nn.attention.sdpa_kernel) set to `EFFICIENT_ATTENTION`. Diffusers pipelines currently do not support setting different `dtypes` for different stages of the pipeline. In order to run inference in the same way as the original implementation, please refer to the following example. + + +The original Mochi implementation zeros out empty prompts. However, enabling this option and placing the entire pipeline under autocast can lead to numerical overflows with the T5 text encoder. + +When enabling `force_zeros_for_empty_prompt`, it is recommended to run the text encoding step outside the autocast context in full precision. + + + +Decoding the latents in full precision is very memory intensive. You will need at least 70GB VRAM to generate the 163 frames in this example. To reduce memory, either reduce the number of frames or run the decoding step in `torch.bfloat16`. + + +```python +import torch +from torch.nn.attention import SDPBackend, sdpa_kernel + +from diffusers import MochiPipeline +from diffusers.utils import export_to_video +from diffusers.video_processor import VideoProcessor + +pipe = MochiPipeline.from_pretrained("genmo/mochi-1-preview", force_zeros_for_empty_prompt=True) +pipe.enable_vae_tiling() +pipe.enable_model_cpu_offload() + +prompt = "An aerial shot of a parade of elephants walking across the African savannah. The camera showcases the herd and the surrounding landscape." + +with torch.no_grad(): + prompt_embeds, prompt_attention_mask, negative_prompt_embeds, negative_prompt_attention_mask = ( + pipe.encode_prompt(prompt=prompt) + ) + +with torch.autocast("cuda", torch.bfloat16): + with sdpa_kernel(SDPBackend.EFFICIENT_ATTENTION): + frames = pipe( + prompt_embeds=prompt_embeds, + prompt_attention_mask=prompt_attention_mask, + negative_prompt_embeds=negative_prompt_embeds, + negative_prompt_attention_mask=negative_prompt_attention_mask, + guidance_scale=4.5, + num_inference_steps=64, + height=480, + width=848, + num_frames=163, + generator=torch.Generator("cuda").manual_seed(0), + output_type="latent", + return_dict=False, + )[0] + +video_processor = VideoProcessor(vae_scale_factor=8) +has_latents_mean = hasattr(pipe.vae.config, "latents_mean") and pipe.vae.config.latents_mean is not None +has_latents_std = hasattr(pipe.vae.config, "latents_std") and pipe.vae.config.latents_std is not None +if has_latents_mean and has_latents_std: + latents_mean = ( + torch.tensor(pipe.vae.config.latents_mean).view(1, 12, 1, 1, 1).to(frames.device, frames.dtype) + ) + latents_std = ( + torch.tensor(pipe.vae.config.latents_std).view(1, 12, 1, 1, 1).to(frames.device, frames.dtype) + ) + frames = frames * latents_std / pipe.vae.config.scaling_factor + latents_mean +else: + frames = frames / pipe.vae.config.scaling_factor + +with torch.no_grad(): + video = pipe.vae.decode(frames.to(pipe.vae.dtype), return_dict=False)[0] + +video = video_processor.postprocess_video(video)[0] +export_to_video(video, "mochi.mp4", fps=30) +``` + +## Running inference with multiple GPUs + +It is possible to split the large Mochi transformer across multiple GPUs using the `device_map` and `max_memory` options in `from_pretrained`. In the following example we split the model across two GPUs, each with 24GB of VRAM. + +```python +import torch +from diffusers import MochiPipeline, MochiTransformer3DModel +from diffusers.utils import export_to_video + +model_id = "genmo/mochi-1-preview" +transformer = MochiTransformer3DModel.from_pretrained( + model_id, + subfolder="transformer", + device_map="auto", + max_memory={0: "24GB", 1: "24GB"} +) + +pipe = MochiPipeline.from_pretrained(model_id, transformer=transformer) +pipe.enable_model_cpu_offload() +pipe.enable_vae_tiling() + +with torch.autocast(device_type="cuda", dtype=torch.bfloat16, cache_enabled=False): + frames = pipe( + prompt="Close-up of a chameleon's eye, with its scaly skin changing color. Ultra high resolution 4k.", + negative_prompt="", + height=480, + width=848, + num_frames=85, + num_inference_steps=50, + guidance_scale=4.5, + num_videos_per_prompt=1, + generator=torch.Generator(device="cuda").manual_seed(0), + max_sequence_length=256, + output_type="pil", + ).frames[0] + +export_to_video(frames, "output.mp4", fps=30) +``` + +## Using single file loading with the Mochi Transformer + +You can use `from_single_file` to load the Mochi transformer in its original format. + + +Diffusers currently doesn't support using the FP8 scaled versions of the Mochi single file checkpoints. + + +```python +import torch +from diffusers import MochiPipeline, MochiTransformer3DModel +from diffusers.utils import export_to_video + +model_id = "genmo/mochi-1-preview" + +ckpt_path = "https://huggingface.co/Comfy-Org/mochi_preview_repackaged/blob/main/split_files/diffusion_models/mochi_preview_bf16.safetensors" + +transformer = MochiTransformer3DModel.from_pretrained(ckpt_path, torch_dtype=torch.bfloat16) + +pipe = MochiPipeline.from_pretrained(model_id, transformer=transformer) +pipe.enable_model_cpu_offload() +pipe.enable_vae_tiling() + +with torch.autocast(device_type="cuda", dtype=torch.bfloat16, cache_enabled=False): + frames = pipe( + prompt="Close-up of a chameleon's eye, with its scaly skin changing color. Ultra high resolution 4k.", + negative_prompt="", + height=480, + width=848, + num_frames=85, + num_inference_steps=50, + guidance_scale=4.5, + num_videos_per_prompt=1, + generator=torch.Generator(device="cuda").manual_seed(0), + max_sequence_length=256, + output_type="pil", + ).frames[0] + +export_to_video(frames, "output.mp4", fps=30) +``` + +## MochiPipeline + +[[autodoc]] MochiPipeline + - all + - __call__ + +## MochiPipelineOutput + +[[autodoc]] pipelines.mochi.pipeline_output.MochiPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/musicldm.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/musicldm.md new file mode 100644 index 0000000000000000000000000000000000000000..412e8e41c2ca5a05f19e8af79cb88f6affa8ab42 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/musicldm.md @@ -0,0 +1,52 @@ + + +# MusicLDM + +MusicLDM was proposed in [MusicLDM: Enhancing Novelty in Text-to-Music Generation Using Beat-Synchronous Mixup Strategies](https://huggingface.co/papers/2308.01546) by Ke Chen, Yusong Wu, Haohe Liu, Marianna Nezhurina, Taylor Berg-Kirkpatrick, Shlomo Dubnov. +MusicLDM takes a text prompt as input and predicts the corresponding music sample. + +Inspired by [Stable Diffusion](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion/overview) and [AudioLDM](https://huggingface.co/docs/diffusers/api/pipelines/audioldm), +MusicLDM is a text-to-music _latent diffusion model (LDM)_ that learns continuous audio representations from [CLAP](https://huggingface.co/docs/transformers/main/model_doc/clap) +latents. + +MusicLDM is trained on a corpus of 466 hours of music data. Beat-synchronous data augmentation strategies are applied to the music samples, both in the time domain and in the latent space. Using beat-synchronous data augmentation strategies encourages the model to interpolate between the training samples, but stay within the domain of the training data. The result is generated music that is more diverse while staying faithful to the corresponding style. + +The abstract of the paper is the following: + +*Diffusion models have shown promising results in cross-modal generation tasks, including text-to-image and text-to-audio generation. However, generating music, as a special type of audio, presents unique challenges due to limited availability of music data and sensitive issues related to copyright and plagiarism. In this paper, to tackle these challenges, we first construct a state-of-the-art text-to-music model, MusicLDM, that adapts Stable Diffusion and AudioLDM architectures to the music domain. We achieve this by retraining the contrastive language-audio pretraining model (CLAP) and the Hifi-GAN vocoder, as components of MusicLDM, on a collection of music data samples. Then, to address the limitations of training data and to avoid plagiarism, we leverage a beat tracking model and propose two different mixup strategies for data augmentation: beat-synchronous audio mixup and beat-synchronous latent mixup, which recombine training audio directly or via a latent embeddings space, respectively. Such mixup strategies encourage the model to interpolate between musical training samples and generate new music within the convex hull of the training data, making the generated music more diverse while still staying faithful to the corresponding style. In addition to popular evaluation metrics, we design several new evaluation metrics based on CLAP score to demonstrate that our proposed MusicLDM and beat-synchronous mixup strategies improve both the quality and novelty of generated music, as well as the correspondence between input text and generated music.* + +This pipeline was contributed by [sanchit-gandhi](https://huggingface.co/sanchit-gandhi). + +## Tips + +When constructing a prompt, keep in mind: + +* Descriptive prompt inputs work best; use adjectives to describe the sound (for example, "high quality" or "clear") and make the prompt context specific where possible (e.g. "melodic techno with a fast beat and synths" works better than "techno"). +* Using a *negative prompt* can significantly improve the quality of the generated audio. Try using a negative prompt of "low quality, average quality". + +During inference: + +* The _quality_ of the generated audio sample can be controlled by the `num_inference_steps` argument; higher steps give higher quality audio at the expense of slower inference. +* Multiple waveforms can be generated in one go: set `num_waveforms_per_prompt` to a value greater than 1 to enable. Automatic scoring will be performed between the generated waveforms and prompt text, and the audios ranked from best to worst accordingly. +* The _length_ of the generated audio sample can be controlled by varying the `audio_length_in_s` argument. + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## MusicLDMPipeline +[[autodoc]] MusicLDMPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/omnigen.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/omnigen.md new file mode 100644 index 0000000000000000000000000000000000000000..ad3a2a68165c6fd9c98502f0231d4dee3f21c483 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/omnigen.md @@ -0,0 +1,80 @@ + + +# OmniGen + +[OmniGen: Unified Image Generation](https://huggingface.co/papers/2409.11340) from BAAI, by Shitao Xiao, Yueze Wang, Junjie Zhou, Huaying Yuan, Xingrun Xing, Ruiran Yan, Chaofan Li, Shuting Wang, Tiejun Huang, Zheng Liu. + +The abstract from the paper is: + +*The emergence of Large Language Models (LLMs) has unified language generation tasks and revolutionized human-machine interaction. However, in the realm of image generation, a unified model capable of handling various tasks within a single framework remains largely unexplored. In this work, we introduce OmniGen, a new diffusion model for unified image generation. OmniGen is characterized by the following features: 1) Unification: OmniGen not only demonstrates text-to-image generation capabilities but also inherently supports various downstream tasks, such as image editing, subject-driven generation, and visual conditional generation. 2) Simplicity: The architecture of OmniGen is highly simplified, eliminating the need for additional plugins. Moreover, compared to existing diffusion models, it is more user-friendly and can complete complex tasks end-to-end through instructions without the need for extra intermediate steps, greatly simplifying the image generation workflow. 3) Knowledge Transfer: Benefit from learning in a unified format, OmniGen effectively transfers knowledge across different tasks, manages unseen tasks and domains, and exhibits novel capabilities. We also explore the model’s reasoning capabilities and potential applications of the chain-of-thought mechanism. This work represents the first attempt at a general-purpose image generation model, and we will release our resources at https://github.com/VectorSpaceLab/OmniGen to foster future advancements.* + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers.md) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading.md#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +This pipeline was contributed by [staoxiao](https://github.com/staoxiao). The original codebase can be found [here](https://github.com/VectorSpaceLab/OmniGen). The original weights can be found under [hf.co/shitao](https://huggingface.co/Shitao/OmniGen-v1). + +## Inference + +First, load the pipeline: + +```python +import torch +from diffusers import OmniGenPipeline + +pipe = OmniGenPipeline.from_pretrained("Shitao/OmniGen-v1-diffusers", torch_dtype=torch.bfloat16) +pipe.to("cuda") +``` + +For text-to-image, pass a text prompt. By default, OmniGen generates a 1024x1024 image. +You can try setting the `height` and `width` parameters to generate images with different size. + +```python +prompt = "Realistic photo. A young woman sits on a sofa, holding a book and facing the camera. She wears delicate silver hoop earrings adorned with tiny, sparkling diamonds that catch the light, with her long chestnut hair cascading over her shoulders. Her eyes are focused and gentle, framed by long, dark lashes. She is dressed in a cozy cream sweater, which complements her warm, inviting smile. Behind her, there is a table with a cup of water in a sleek, minimalist blue mug. The background is a serene indoor setting with soft natural light filtering through a window, adorned with tasteful art and flowers, creating a cozy and peaceful ambiance. 4K, HD." +image = pipe( + prompt=prompt, + height=1024, + width=1024, + guidance_scale=3, + generator=torch.Generator(device="cpu").manual_seed(111), +).images[0] +image.save("output.png") +``` + +OmniGen supports multimodal inputs. +When the input includes an image, you need to add a placeholder `<|image_1|>` in the text prompt to represent the image. +It is recommended to enable `use_input_image_size_as_output` to keep the edited image the same size as the original image. + +```python +prompt="<|image_1|> Remove the woman's earrings. Replace the mug with a clear glass filled with sparkling iced cola." +input_images=[load_image("https://raw.githubusercontent.com/VectorSpaceLab/OmniGen/main/imgs/docs_img/t2i_woman_with_book.png")] +image = pipe( + prompt=prompt, + input_images=input_images, + guidance_scale=2, + img_guidance_scale=1.6, + use_input_image_size_as_output=True, + generator=torch.Generator(device="cpu").manual_seed(222)).images[0] +image.save("output.png") +``` + +## OmniGenPipeline + +[[autodoc]] OmniGenPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/overview.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/overview.md new file mode 100644 index 0000000000000000000000000000000000000000..95b50ce60826eaebfc6aabde6c3a228e4739a98e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/overview.md @@ -0,0 +1,114 @@ + + +# Pipelines + +Pipelines provide a simple way to run state-of-the-art diffusion models in inference by bundling all of the necessary components (multiple independently-trained models, schedulers, and processors) into a single end-to-end class. Pipelines are flexible and they can be adapted to use different schedulers or even model components. + +All pipelines are built from the base [`DiffusionPipeline`] class which provides basic functionality for loading, downloading, and saving all the components. Specific pipeline types (for example [`StableDiffusionPipeline`]) loaded with [`~DiffusionPipeline.from_pretrained`] are automatically detected and the pipeline components are loaded and passed to the `__init__` function of the pipeline. + + + +You shouldn't use the [`DiffusionPipeline`] class for training. Individual components (for example, [`UNet2DModel`] and [`UNet2DConditionModel`]) of diffusion pipelines are usually trained individually, so we suggest directly working with them instead. + +
+ +Pipelines do not offer any training functionality. You'll notice PyTorch's autograd is disabled by decorating the [`~DiffusionPipeline.__call__`] method with a [`torch.no_grad`](https://pytorch.org/docs/stable/generated/torch.no_grad.html) decorator because pipelines should not be used for training. If you're interested in training, please take a look at the [Training](../../training/overview) guides instead! + +
+ +The table below lists all the pipelines currently available in 🤗 Diffusers and the tasks they support. Click on a pipeline to view its abstract and published paper. + +| Pipeline | Tasks | +|---|---| +| [aMUSEd](amused) | text2image | +| [AnimateDiff](animatediff) | text2video | +| [Attend-and-Excite](attend_and_excite) | text2image | +| [AudioLDM](audioldm) | text2audio | +| [AudioLDM2](audioldm2) | text2audio | +| [AuraFlow](auraflow) | text2image | +| [BLIP Diffusion](blip_diffusion) | text2image | +| [CogVideoX](cogvideox) | text2video | +| [Consistency Models](consistency_models) | unconditional image generation | +| [ControlNet](controlnet) | text2image, image2image, inpainting | +| [ControlNet with Flux.1](controlnet_flux) | text2image | +| [ControlNet with Hunyuan-DiT](controlnet_hunyuandit) | text2image | +| [ControlNet with Stable Diffusion 3](controlnet_sd3) | text2image | +| [ControlNet with Stable Diffusion XL](controlnet_sdxl) | text2image | +| [ControlNet-XS](controlnetxs) | text2image | +| [ControlNet-XS with Stable Diffusion XL](controlnetxs_sdxl) | text2image | +| [Dance Diffusion](dance_diffusion) | unconditional audio generation | +| [DDIM](ddim) | unconditional image generation | +| [DDPM](ddpm) | unconditional image generation | +| [DeepFloyd IF](deepfloyd_if) | text2image, image2image, inpainting, super-resolution | +| [DiffEdit](diffedit) | inpainting | +| [DiT](dit) | text2image | +| [Flux](flux) | text2image | +| [Hunyuan-DiT](hunyuandit) | text2image | +| [I2VGen-XL](i2vgenxl) | image2video | +| [InstructPix2Pix](pix2pix) | image editing | +| [Kandinsky 2.1](kandinsky) | text2image, image2image, inpainting, interpolation | +| [Kandinsky 2.2](kandinsky_v22) | text2image, image2image, inpainting | +| [Kandinsky 3](kandinsky3) | text2image, image2image | +| [Kolors](kolors) | text2image | +| [Latent Consistency Models](latent_consistency_models) | text2image | +| [Latent Diffusion](latent_diffusion) | text2image, super-resolution | +| [Latte](latte) | text2image | +| [LEDITS++](ledits_pp) | image editing | +| [Lumina-T2X](lumina) | text2image | +| [Marigold](marigold) | depth-estimation, normals-estimation, intrinsic-decomposition | +| [MultiDiffusion](panorama) | text2image | +| [MusicLDM](musicldm) | text2audio | +| [PAG](pag) | text2image | +| [Paint by Example](paint_by_example) | inpainting | +| [PIA](pia) | image2video | +| [PixArt-α](pixart) | text2image | +| [PixArt-Σ](pixart_sigma) | text2image | +| [Self-Attention Guidance](self_attention_guidance) | text2image | +| [Semantic Guidance](semantic_stable_diffusion) | text2image | +| [Shap-E](shap_e) | text-to-3D, image-to-3D | +| [Stable Audio](stable_audio) | text2audio | +| [Stable Cascade](stable_cascade) | text2image | +| [Stable Diffusion](stable_diffusion/overview) | text2image, image2image, depth2image, inpainting, image variation, latent upscaler, super-resolution | +| [Stable Diffusion XL](stable_diffusion/stable_diffusion_xl) | text2image, image2image, inpainting | +| [Stable Diffusion XL Turbo](stable_diffusion/sdxl_turbo) | text2image, image2image, inpainting | +| [Stable unCLIP](stable_unclip) | text2image, image variation | +| [T2I-Adapter](stable_diffusion/adapter) | text2image | +| [Text2Video](text_to_video) | text2video, video2video | +| [Text2Video-Zero](text_to_video_zero) | text2video | +| [unCLIP](unclip) | text2image, image variation | +| [UniDiffuser](unidiffuser) | text2image, image2text, image variation, text variation, unconditional image generation, unconditional audio generation | +| [Value-guided planning](value_guided_sampling) | value guided sampling | +| [Wuerstchen](wuerstchen) | text2image | +| [VisualCloze](visualcloze) | text2image, image2image, subject driven generation, inpainting, style transfer, image restoration, image editing, [depth,normal,edge,pose]2image, [depth,normal,edge,pose]-estimation, virtual try-on, image relighting | + +## DiffusionPipeline + +[[autodoc]] DiffusionPipeline + - all + - __call__ + - device + - to + - components + + +[[autodoc]] pipelines.StableDiffusionMixin.enable_freeu + +[[autodoc]] pipelines.StableDiffusionMixin.disable_freeu + +## FlaxDiffusionPipeline + +[[autodoc]] pipelines.pipeline_flax_utils.FlaxDiffusionPipeline + +## PushToHubMixin + +[[autodoc]] utils.PushToHubMixin diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pag.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pag.md new file mode 100644 index 0000000000000000000000000000000000000000..64aefdf7e78f3d1e36ae9ca3a7af3d97d73537ef --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pag.md @@ -0,0 +1,116 @@ + + +# Perturbed-Attention Guidance + +
+ LoRA +
+ +[Perturbed-Attention Guidance (PAG)](https://ku-cvlab.github.io/Perturbed-Attention-Guidance/) is a new diffusion sampling guidance that improves sample quality across both unconditional and conditional settings, achieving this without requiring further training or the integration of external modules. + +PAG was introduced in [Self-Rectifying Diffusion Sampling with Perturbed-Attention Guidance](https://huggingface.co/papers/2403.17377) by Donghoon Ahn, Hyoungwon Cho, Jaewon Min, Wooseok Jang, Jungwoo Kim, SeonHwa Kim, Hyun Hee Park, Kyong Hwan Jin and Seungryong Kim. + +The abstract from the paper is: + +*Recent studies have demonstrated that diffusion models are capable of generating high-quality samples, but their quality heavily depends on sampling guidance techniques, such as classifier guidance (CG) and classifier-free guidance (CFG). These techniques are often not applicable in unconditional generation or in various downstream tasks such as image restoration. In this paper, we propose a novel sampling guidance, called Perturbed-Attention Guidance (PAG), which improves diffusion sample quality across both unconditional and conditional settings, achieving this without requiring additional training or the integration of external modules. PAG is designed to progressively enhance the structure of samples throughout the denoising process. It involves generating intermediate samples with degraded structure by substituting selected self-attention maps in diffusion U-Net with an identity matrix, by considering the self-attention mechanisms' ability to capture structural information, and guiding the denoising process away from these degraded samples. In both ADM and Stable Diffusion, PAG surprisingly improves sample quality in conditional and even unconditional scenarios. Moreover, PAG significantly improves the baseline performance in various downstream tasks where existing guidances such as CG or CFG cannot be fully utilized, including ControlNet with empty prompts and image restoration such as inpainting and deblurring.* + +PAG can be used by specifying the `pag_applied_layers` as a parameter when instantiating a PAG pipeline. It can be a single string or a list of strings. Each string can be a unique layer identifier or a regular expression to identify one or more layers. + +- Full identifier as a normal string: `down_blocks.2.attentions.0.transformer_blocks.0.attn1.processor` +- Full identifier as a RegEx: `down_blocks.2.(attentions|motion_modules).0.transformer_blocks.0.attn1.processor` +- Partial identifier as a RegEx: `down_blocks.2`, or `attn1` +- List of identifiers (can be combo of strings and ReGex): `["blocks.1", "blocks.(14|20)", r"down_blocks\.(2,3)"]` + + + +Since RegEx is supported as a way for matching layer identifiers, it is crucial to use it correctly otherwise there might be unexpected behaviour. The recommended way to use PAG is by specifying layers as `blocks.{layer_index}` and `blocks.({layer_index_1|layer_index_2|...})`. Using it in any other way, while doable, may bypass our basic validation checks and give you unexpected results. + + + +## AnimateDiffPAGPipeline +[[autodoc]] AnimateDiffPAGPipeline + - all + - __call__ + +## HunyuanDiTPAGPipeline +[[autodoc]] HunyuanDiTPAGPipeline + - all + - __call__ + +## KolorsPAGPipeline +[[autodoc]] KolorsPAGPipeline + - all + - __call__ + +## StableDiffusionPAGInpaintPipeline +[[autodoc]] StableDiffusionPAGInpaintPipeline + - all + - __call__ + +## StableDiffusionPAGPipeline +[[autodoc]] StableDiffusionPAGPipeline + - all + - __call__ + +## StableDiffusionPAGImg2ImgPipeline +[[autodoc]] StableDiffusionPAGImg2ImgPipeline + - all + - __call__ + +## StableDiffusionControlNetPAGPipeline +[[autodoc]] StableDiffusionControlNetPAGPipeline + +## StableDiffusionControlNetPAGInpaintPipeline +[[autodoc]] StableDiffusionControlNetPAGInpaintPipeline + - all + - __call__ + +## StableDiffusionXLPAGPipeline +[[autodoc]] StableDiffusionXLPAGPipeline + - all + - __call__ + +## StableDiffusionXLPAGImg2ImgPipeline +[[autodoc]] StableDiffusionXLPAGImg2ImgPipeline + - all + - __call__ + +## StableDiffusionXLPAGInpaintPipeline +[[autodoc]] StableDiffusionXLPAGInpaintPipeline + - all + - __call__ + +## StableDiffusionXLControlNetPAGPipeline +[[autodoc]] StableDiffusionXLControlNetPAGPipeline + - all + - __call__ + +## StableDiffusionXLControlNetPAGImg2ImgPipeline +[[autodoc]] StableDiffusionXLControlNetPAGImg2ImgPipeline + - all + - __call__ + +## StableDiffusion3PAGPipeline +[[autodoc]] StableDiffusion3PAGPipeline + - all + - __call__ + +## StableDiffusion3PAGImg2ImgPipeline +[[autodoc]] StableDiffusion3PAGImg2ImgPipeline + - all + - __call__ + +## PixArtSigmaPAGPipeline +[[autodoc]] PixArtSigmaPAGPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/paint_by_example.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/paint_by_example.md new file mode 100644 index 0000000000000000000000000000000000000000..75360596d67679315477f28a6663e7b2ca42febe --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/paint_by_example.md @@ -0,0 +1,39 @@ + + +# Paint by Example + +[Paint by Example: Exemplar-based Image Editing with Diffusion Models](https://huggingface.co/papers/2211.13227) is by Binxin Yang, Shuyang Gu, Bo Zhang, Ting Zhang, Xuejin Chen, Xiaoyan Sun, Dong Chen, Fang Wen. + +The abstract from the paper is: + +*Language-guided image editing has achieved great success recently. In this paper, for the first time, we investigate exemplar-guided image editing for more precise control. We achieve this goal by leveraging self-supervised training to disentangle and re-organize the source image and the exemplar. However, the naive approach will cause obvious fusing artifacts. We carefully analyze it and propose an information bottleneck and strong augmentations to avoid the trivial solution of directly copying and pasting the exemplar image. Meanwhile, to ensure the controllability of the editing process, we design an arbitrary shape mask for the exemplar image and leverage the classifier-free guidance to increase the similarity to the exemplar image. The whole framework involves a single forward of the diffusion model without any iterative optimization. We demonstrate that our method achieves an impressive performance and enables controllable editing on in-the-wild images with high fidelity.* + +The original codebase can be found at [Fantasy-Studio/Paint-by-Example](https://github.com/Fantasy-Studio/Paint-by-Example), and you can try it out in a [demo](https://huggingface.co/spaces/Fantasy-Studio/Paint-by-Example). + +## Tips + +Paint by Example is supported by the official [Fantasy-Studio/Paint-by-Example](https://huggingface.co/Fantasy-Studio/Paint-by-Example) checkpoint. The checkpoint is warm-started from [CompVis/stable-diffusion-v1-4](https://huggingface.co/CompVis/stable-diffusion-v1-4) to inpaint partly masked images conditioned on example and reference images. + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## PaintByExamplePipeline +[[autodoc]] PaintByExamplePipeline + - all + - __call__ + +## StableDiffusionPipelineOutput +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/panorama.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/panorama.md new file mode 100644 index 0000000000000000000000000000000000000000..cbd5aaf815dbc649e4c6f8a615f1ae526ca0c130 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/panorama.md @@ -0,0 +1,54 @@ + + +# MultiDiffusion + +
+ LoRA +
+ +[MultiDiffusion: Fusing Diffusion Paths for Controlled Image Generation](https://huggingface.co/papers/2302.08113) is by Omer Bar-Tal, Lior Yariv, Yaron Lipman, and Tali Dekel. + +The abstract from the paper is: + +*Recent advances in text-to-image generation with diffusion models present transformative capabilities in image quality. However, user controllability of the generated image, and fast adaptation to new tasks still remains an open challenge, currently mostly addressed by costly and long re-training and fine-tuning or ad-hoc adaptations to specific image generation tasks. In this work, we present MultiDiffusion, a unified framework that enables versatile and controllable image generation, using a pre-trained text-to-image diffusion model, without any further training or finetuning. At the center of our approach is a new generation process, based on an optimization task that binds together multiple diffusion generation processes with a shared set of parameters or constraints. We show that MultiDiffusion can be readily applied to generate high quality and diverse images that adhere to user-provided controls, such as desired aspect ratio (e.g., panorama), and spatial guiding signals, ranging from tight segmentation masks to bounding boxes.* + +You can find additional information about MultiDiffusion on the [project page](https://multidiffusion.github.io/), [original codebase](https://github.com/omerbt/MultiDiffusion), and try it out in a [demo](https://huggingface.co/spaces/weizmannscience/MultiDiffusion). + +## Tips + +While calling [`StableDiffusionPanoramaPipeline`], it's possible to specify the `view_batch_size` parameter to be > 1. +For some GPUs with high performance, this can speedup the generation process and increase VRAM usage. + +To generate panorama-like images make sure you pass the width parameter accordingly. We recommend a width value of 2048 which is the default. + +Circular padding is applied to ensure there are no stitching artifacts when working with panoramas to ensure a seamless transition from the rightmost part to the leftmost part. By enabling circular padding (set `circular_padding=True`), the operation applies additional crops after the rightmost point of the image, allowing the model to "see” the transition from the rightmost part to the leftmost part. This helps maintain visual consistency in a 360-degree sense and creates a proper “panorama” that can be viewed using 360-degree panorama viewers. When decoding latents in Stable Diffusion, circular padding is applied to ensure that the decoded latents match in the RGB space. + +For example, without circular padding, there is a stitching artifact (default): +![img](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/indoor_%20no_circular_padding.png) + +But with circular padding, the right and the left parts are matching (`circular_padding=True`): +![img](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/indoor_%20circular_padding.png) + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## StableDiffusionPanoramaPipeline +[[autodoc]] StableDiffusionPanoramaPipeline + - __call__ + - all + +## StableDiffusionPipelineOutput +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pia.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pia.md new file mode 100644 index 0000000000000000000000000000000000000000..4793829aed784e3c73f303bb3ef77ac354bad5d8 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pia.md @@ -0,0 +1,171 @@ + + +# Image-to-Video Generation with PIA (Personalized Image Animator) + +
+ LoRA +
+ +## Overview + +[PIA: Your Personalized Image Animator via Plug-and-Play Modules in Text-to-Image Models](https://huggingface.co/papers/2312.13964) by Yiming Zhang, Zhening Xing, Yanhong Zeng, Youqing Fang, Kai Chen + +Recent advancements in personalized text-to-image (T2I) models have revolutionized content creation, empowering non-experts to generate stunning images with unique styles. While promising, adding realistic motions into these personalized images by text poses significant challenges in preserving distinct styles, high-fidelity details, and achieving motion controllability by text. In this paper, we present PIA, a Personalized Image Animator that excels in aligning with condition images, achieving motion controllability by text, and the compatibility with various personalized T2I models without specific tuning. To achieve these goals, PIA builds upon a base T2I model with well-trained temporal alignment layers, allowing for the seamless transformation of any personalized T2I model into an image animation model. A key component of PIA is the introduction of the condition module, which utilizes the condition frame and inter-frame affinity as input to transfer appearance information guided by the affinity hint for individual frame synthesis in the latent space. This design mitigates the challenges of appearance-related image alignment within and allows for a stronger focus on aligning with motion-related guidance. + +[Project page](https://pi-animator.github.io/) + +## Available Pipelines + +| Pipeline | Tasks | Demo +|---|---|:---:| +| [PIAPipeline](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/pia/pipeline_pia.py) | *Image-to-Video Generation with PIA* | + +## Available checkpoints + +Motion Adapter checkpoints for PIA can be found under the [OpenMMLab org](https://huggingface.co/openmmlab/PIA-condition-adapter). These checkpoints are meant to work with any model based on Stable Diffusion 1.5 + +## Usage example + +PIA works with a MotionAdapter checkpoint and a Stable Diffusion 1.5 model checkpoint. The MotionAdapter is a collection of Motion Modules that are responsible for adding coherent motion across image frames. These modules are applied after the Resnet and Attention blocks in the Stable Diffusion UNet. In addition to the motion modules, PIA also replaces the input convolution layer of the SD 1.5 UNet model with a 9 channel input convolution layer. + +The following example demonstrates how to use PIA to generate a video from a single image. + +```python +import torch +from diffusers import ( + EulerDiscreteScheduler, + MotionAdapter, + PIAPipeline, +) +from diffusers.utils import export_to_gif, load_image + +adapter = MotionAdapter.from_pretrained("openmmlab/PIA-condition-adapter") +pipe = PIAPipeline.from_pretrained("SG161222/Realistic_Vision_V6.0_B1_noVAE", motion_adapter=adapter, torch_dtype=torch.float16) + +pipe.scheduler = EulerDiscreteScheduler.from_config(pipe.scheduler.config) +pipe.enable_model_cpu_offload() +pipe.enable_vae_slicing() + +image = load_image( + "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/pix2pix/cat_6.png?download=true" +) +image = image.resize((512, 512)) +prompt = "cat in a field" +negative_prompt = "wrong white balance, dark, sketches,worst quality,low quality" + +generator = torch.Generator("cpu").manual_seed(0) +output = pipe(image=image, prompt=prompt, generator=generator) +frames = output.frames[0] +export_to_gif(frames, "pia-animation.gif") +``` + +Here are some sample outputs: + + + + + +
+ cat in a field. +
+ cat in a field +
+ + + + +If you plan on using a scheduler that can clip samples, make sure to disable it by setting `clip_sample=False` in the scheduler as this can also have an adverse effect on generated samples. Additionally, the PIA checkpoints can be sensitive to the beta schedule of the scheduler. We recommend setting this to `linear`. + + + +## Using FreeInit + +[FreeInit: Bridging Initialization Gap in Video Diffusion Models](https://huggingface.co/papers/2312.07537) by Tianxing Wu, Chenyang Si, Yuming Jiang, Ziqi Huang, Ziwei Liu. + +FreeInit is an effective method that improves temporal consistency and overall quality of videos generated using video-diffusion-models without any addition training. It can be applied to PIA, AnimateDiff, ModelScope, VideoCrafter and various other video generation models seamlessly at inference time, and works by iteratively refining the latent-initialization noise. More details can be found it the paper. + +The following example demonstrates the usage of FreeInit. + +```python +import torch +from diffusers import ( + DDIMScheduler, + MotionAdapter, + PIAPipeline, +) +from diffusers.utils import export_to_gif, load_image + +adapter = MotionAdapter.from_pretrained("openmmlab/PIA-condition-adapter") +pipe = PIAPipeline.from_pretrained("SG161222/Realistic_Vision_V6.0_B1_noVAE", motion_adapter=adapter) + +# enable FreeInit +# Refer to the enable_free_init documentation for a full list of configurable parameters +pipe.enable_free_init(method="butterworth", use_fast_sampling=True) + +# Memory saving options +pipe.enable_model_cpu_offload() +pipe.enable_vae_slicing() + +pipe.scheduler = DDIMScheduler.from_config(pipe.scheduler.config) +image = load_image( + "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/pix2pix/cat_6.png?download=true" +) +image = image.resize((512, 512)) +prompt = "cat in a field" +negative_prompt = "wrong white balance, dark, sketches,worst quality,low quality" + +generator = torch.Generator("cpu").manual_seed(0) + +output = pipe(image=image, prompt=prompt, generator=generator) +frames = output.frames[0] +export_to_gif(frames, "pia-freeinit-animation.gif") +``` + + + + + +
+ cat in a field. +
+ cat in a field +
+ + + + +FreeInit is not really free - the improved quality comes at the cost of extra computation. It requires sampling a few extra times depending on the `num_iters` parameter that is set when enabling it. Setting the `use_fast_sampling` parameter to `True` can improve the overall performance (at the cost of lower quality compared to when `use_fast_sampling=False` but still better results than vanilla video generation models). + + + +## PIAPipeline + +[[autodoc]] PIAPipeline + - all + - __call__ + - enable_freeu + - disable_freeu + - enable_free_init + - disable_free_init + - enable_vae_slicing + - disable_vae_slicing + - enable_vae_tiling + - disable_vae_tiling + +## PIAPipelineOutput + +[[autodoc]] pipelines.pia.PIAPipelineOutput \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pix2pix.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pix2pix.md new file mode 100644 index 0000000000000000000000000000000000000000..d0b3bf32b8231d0fcafda407e55bd2034d5cf918 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pix2pix.md @@ -0,0 +1,44 @@ + + +# InstructPix2Pix + +
+ LoRA +
+ +[InstructPix2Pix: Learning to Follow Image Editing Instructions](https://huggingface.co/papers/2211.09800) is by Tim Brooks, Aleksander Holynski and Alexei A. Efros. + +The abstract from the paper is: + +*We propose a method for editing images from human instructions: given an input image and a written instruction that tells the model what to do, our model follows these instructions to edit the image. To obtain training data for this problem, we combine the knowledge of two large pretrained models -- a language model (GPT-3) and a text-to-image model (Stable Diffusion) -- to generate a large dataset of image editing examples. Our conditional diffusion model, InstructPix2Pix, is trained on our generated data, and generalizes to real images and user-written instructions at inference time. Since it performs edits in the forward pass and does not require per example fine-tuning or inversion, our model edits images quickly, in a matter of seconds. We show compelling editing results for a diverse collection of input images and written instructions.* + +You can find additional information about InstructPix2Pix on the [project page](https://www.timothybrooks.com/instruct-pix2pix), [original codebase](https://github.com/timothybrooks/instruct-pix2pix), and try it out in a [demo](https://huggingface.co/spaces/timbrooks/instruct-pix2pix). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## StableDiffusionInstructPix2PixPipeline +[[autodoc]] StableDiffusionInstructPix2PixPipeline + - __call__ + - all + - load_textual_inversion + - load_lora_weights + - save_lora_weights + +## StableDiffusionXLInstructPix2PixPipeline +[[autodoc]] StableDiffusionXLInstructPix2PixPipeline + - __call__ + - all diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pixart.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pixart.md new file mode 100644 index 0000000000000000000000000000000000000000..d4e268b81d490d98931a85d0b282b0f2ef7c8d6b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pixart.md @@ -0,0 +1,148 @@ + + +# PixArt-α + +![](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/pixart/header_collage.png) + +[PixArt-α: Fast Training of Diffusion Transformer for Photorealistic Text-to-Image Synthesis](https://huggingface.co/papers/2310.00426) is Junsong Chen, Jincheng Yu, Chongjian Ge, Lewei Yao, Enze Xie, Yue Wu, Zhongdao Wang, James Kwok, Ping Luo, Huchuan Lu, and Zhenguo Li. + +The abstract from the paper is: + +*The most advanced text-to-image (T2I) models require significant training costs (e.g., millions of GPU hours), seriously hindering the fundamental innovation for the AIGC community while increasing CO2 emissions. This paper introduces PIXART-α, a Transformer-based T2I diffusion model whose image generation quality is competitive with state-of-the-art image generators (e.g., Imagen, SDXL, and even Midjourney), reaching near-commercial application standards. Additionally, it supports high-resolution image synthesis up to 1024px resolution with low training cost, as shown in Figure 1 and 2. To achieve this goal, three core designs are proposed: (1) Training strategy decomposition: We devise three distinct training steps that separately optimize pixel dependency, text-image alignment, and image aesthetic quality; (2) Efficient T2I Transformer: We incorporate cross-attention modules into Diffusion Transformer (DiT) to inject text conditions and streamline the computation-intensive class-condition branch; (3) High-informative data: We emphasize the significance of concept density in text-image pairs and leverage a large Vision-Language model to auto-label dense pseudo-captions to assist text-image alignment learning. As a result, PIXART-α's training speed markedly surpasses existing large-scale T2I models, e.g., PIXART-α only takes 10.8% of Stable Diffusion v1.5's training time (675 vs. 6,250 A100 GPU days), saving nearly $300,000 ($26,000 vs. $320,000) and reducing 90% CO2 emissions. Moreover, compared with a larger SOTA model, RAPHAEL, our training cost is merely 1%. Extensive experiments demonstrate that PIXART-α excels in image quality, artistry, and semantic control. We hope PIXART-α will provide new insights to the AIGC community and startups to accelerate building their own high-quality yet low-cost generative models from scratch.* + +You can find the original codebase at [PixArt-alpha/PixArt-alpha](https://github.com/PixArt-alpha/PixArt-alpha) and all the available checkpoints at [PixArt-alpha](https://huggingface.co/PixArt-alpha). + +Some notes about this pipeline: + +* It uses a Transformer backbone (instead of a UNet) for denoising. As such it has a similar architecture as [DiT](./dit). +* It was trained using text conditions computed from T5. This aspect makes the pipeline better at following complex text prompts with intricate details. +* It is good at producing high-resolution images at different aspect ratios. To get the best results, the authors recommend some size brackets which can be found [here](https://github.com/PixArt-alpha/PixArt-alpha/blob/08fbbd281ec96866109bdd2cdb75f2f58fb17610/diffusion/data/datasets/utils.py). +* It rivals the quality of state-of-the-art text-to-image generation systems (as of this writing) such as Stable Diffusion XL, Imagen, and DALL-E 2, while being more efficient than them. + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## Inference with under 8GB GPU VRAM + +Run the [`PixArtAlphaPipeline`] with under 8GB GPU VRAM by loading the text encoder in 8-bit precision. Let's walk through a full-fledged example. + +First, install the [bitsandbytes](https://github.com/TimDettmers/bitsandbytes) library: + +```bash +pip install -U bitsandbytes +``` + +Then load the text encoder in 8-bit: + +```python +from transformers import T5EncoderModel +from diffusers import PixArtAlphaPipeline +import torch + +text_encoder = T5EncoderModel.from_pretrained( + "PixArt-alpha/PixArt-XL-2-1024-MS", + subfolder="text_encoder", + load_in_8bit=True, + device_map="auto", + +) +pipe = PixArtAlphaPipeline.from_pretrained( + "PixArt-alpha/PixArt-XL-2-1024-MS", + text_encoder=text_encoder, + transformer=None, + device_map="auto" +) +``` + +Now, use the `pipe` to encode a prompt: + +```python +with torch.no_grad(): + prompt = "cute cat" + prompt_embeds, prompt_attention_mask, negative_embeds, negative_prompt_attention_mask = pipe.encode_prompt(prompt) +``` + +Since text embeddings have been computed, remove the `text_encoder` and `pipe` from the memory, and free up some GPU VRAM: + +```python +import gc + +def flush(): + gc.collect() + torch.cuda.empty_cache() + +del text_encoder +del pipe +flush() +``` + +Then compute the latents with the prompt embeddings as inputs: + +```python +pipe = PixArtAlphaPipeline.from_pretrained( + "PixArt-alpha/PixArt-XL-2-1024-MS", + text_encoder=None, + torch_dtype=torch.float16, +).to("cuda") + +latents = pipe( + negative_prompt=None, + prompt_embeds=prompt_embeds, + negative_prompt_embeds=negative_embeds, + prompt_attention_mask=prompt_attention_mask, + negative_prompt_attention_mask=negative_prompt_attention_mask, + num_images_per_prompt=1, + output_type="latent", +).images + +del pipe.transformer +flush() +``` + + + +Notice that while initializing `pipe`, you're setting `text_encoder` to `None` so that it's not loaded. + + + +Once the latents are computed, pass it off to the VAE to decode into a real image: + +```python +with torch.no_grad(): + image = pipe.vae.decode(latents / pipe.vae.config.scaling_factor, return_dict=False)[0] +image = pipe.image_processor.postprocess(image, output_type="pil")[0] +image.save("cat.png") +``` + +By deleting components you aren't using and flushing the GPU VRAM, you should be able to run [`PixArtAlphaPipeline`] with under 8GB GPU VRAM. + +![](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/pixart/8bits_cat.png) + +If you want a report of your memory-usage, run this [script](https://gist.github.com/sayakpaul/3ae0f847001d342af27018a96f467e4e). + + + +Text embeddings computed in 8-bit can impact the quality of the generated images because of the information loss in the representation space caused by the reduced precision. It's recommended to compare the outputs with and without 8-bit. + + + +While loading the `text_encoder`, you set `load_in_8bit` to `True`. You could also specify `load_in_4bit` to bring your memory requirements down even further to under 7GB. + +## PixArtAlphaPipeline + +[[autodoc]] PixArtAlphaPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pixart_sigma.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pixart_sigma.md new file mode 100644 index 0000000000000000000000000000000000000000..592ba0f374bea6c57e23d2829154397ce4b1f701 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/pixart_sigma.md @@ -0,0 +1,155 @@ + + +# PixArt-Σ + +![](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/pixart/header_collage_sigma.jpg) + +[PixArt-Σ: Weak-to-Strong Training of Diffusion Transformer for 4K Text-to-Image Generation](https://huggingface.co/papers/2403.04692) is Junsong Chen, Jincheng Yu, Chongjian Ge, Lewei Yao, Enze Xie, Yue Wu, Zhongdao Wang, James Kwok, Ping Luo, Huchuan Lu, and Zhenguo Li. + +The abstract from the paper is: + +*In this paper, we introduce PixArt-Σ, a Diffusion Transformer model (DiT) capable of directly generating images at 4K resolution. PixArt-Σ represents a significant advancement over its predecessor, PixArt-α, offering images of markedly higher fidelity and improved alignment with text prompts. A key feature of PixArt-Σ is its training efficiency. Leveraging the foundational pre-training of PixArt-α, it evolves from the ‘weaker’ baseline to a ‘stronger’ model via incorporating higher quality data, a process we term “weak-to-strong training”. The advancements in PixArt-Σ are twofold: (1) High-Quality Training Data: PixArt-Σ incorporates superior-quality image data, paired with more precise and detailed image captions. (2) Efficient Token Compression: we propose a novel attention module within the DiT framework that compresses both keys and values, significantly improving efficiency and facilitating ultra-high-resolution image generation. Thanks to these improvements, PixArt-Σ achieves superior image quality and user prompt adherence capabilities with significantly smaller model size (0.6B parameters) than existing text-to-image diffusion models, such as SDXL (2.6B parameters) and SD Cascade (5.1B parameters). Moreover, PixArt-Σ’s capability to generate 4K images supports the creation of high-resolution posters and wallpapers, efficiently bolstering the production of highquality visual content in industries such as film and gaming.* + +You can find the original codebase at [PixArt-alpha/PixArt-sigma](https://github.com/PixArt-alpha/PixArt-sigma) and all the available checkpoints at [PixArt-alpha](https://huggingface.co/PixArt-alpha). + +Some notes about this pipeline: + +* It uses a Transformer backbone (instead of a UNet) for denoising. As such it has a similar architecture as [DiT](https://hf.co/docs/transformers/model_doc/dit). +* It was trained using text conditions computed from T5. This aspect makes the pipeline better at following complex text prompts with intricate details. +* It is good at producing high-resolution images at different aspect ratios. To get the best results, the authors recommend some size brackets which can be found [here](https://github.com/PixArt-alpha/PixArt-sigma/blob/master/diffusion/data/datasets/utils.py). +* It rivals the quality of state-of-the-art text-to-image generation systems (as of this writing) such as PixArt-α, Stable Diffusion XL, Playground V2.0 and DALL-E 3, while being more efficient than them. +* It shows the ability of generating super high resolution images, such as 2048px or even 4K. +* It shows that text-to-image models can grow from a weak model to a stronger one through several improvements (VAEs, datasets, and so on.) + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + + + +You can further improve generation quality by passing the generated image from [`PixArtSigmaPipeline`] to the [SDXL refiner](../../using-diffusers/sdxl#base-to-refiner-model) model. + + + +## Inference with under 8GB GPU VRAM + +Run the [`PixArtSigmaPipeline`] with under 8GB GPU VRAM by loading the text encoder in 8-bit precision. Let's walk through a full-fledged example. + +First, install the [bitsandbytes](https://github.com/TimDettmers/bitsandbytes) library: + +```bash +pip install -U bitsandbytes +``` + +Then load the text encoder in 8-bit: + +```python +from transformers import T5EncoderModel +from diffusers import PixArtSigmaPipeline +import torch + +text_encoder = T5EncoderModel.from_pretrained( + "PixArt-alpha/PixArt-Sigma-XL-2-1024-MS", + subfolder="text_encoder", + load_in_8bit=True, + device_map="auto", +) +pipe = PixArtSigmaPipeline.from_pretrained( + "PixArt-alpha/PixArt-Sigma-XL-2-1024-MS", + text_encoder=text_encoder, + transformer=None, + device_map="balanced" +) +``` + +Now, use the `pipe` to encode a prompt: + +```python +with torch.no_grad(): + prompt = "cute cat" + prompt_embeds, prompt_attention_mask, negative_embeds, negative_prompt_attention_mask = pipe.encode_prompt(prompt) +``` + +Since text embeddings have been computed, remove the `text_encoder` and `pipe` from the memory, and free up some GPU VRAM: + +```python +import gc + +def flush(): + gc.collect() + torch.cuda.empty_cache() + +del text_encoder +del pipe +flush() +``` + +Then compute the latents with the prompt embeddings as inputs: + +```python +pipe = PixArtSigmaPipeline.from_pretrained( + "PixArt-alpha/PixArt-Sigma-XL-2-1024-MS", + text_encoder=None, + torch_dtype=torch.float16, +).to("cuda") + +latents = pipe( + negative_prompt=None, + prompt_embeds=prompt_embeds, + negative_prompt_embeds=negative_embeds, + prompt_attention_mask=prompt_attention_mask, + negative_prompt_attention_mask=negative_prompt_attention_mask, + num_images_per_prompt=1, + output_type="latent", +).images + +del pipe.transformer +flush() +``` + + + +Notice that while initializing `pipe`, you're setting `text_encoder` to `None` so that it's not loaded. + + + +Once the latents are computed, pass it off to the VAE to decode into a real image: + +```python +with torch.no_grad(): + image = pipe.vae.decode(latents / pipe.vae.config.scaling_factor, return_dict=False)[0] +image = pipe.image_processor.postprocess(image, output_type="pil")[0] +image.save("cat.png") +``` + +By deleting components you aren't using and flushing the GPU VRAM, you should be able to run [`PixArtSigmaPipeline`] with under 8GB GPU VRAM. + +![](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/pixart/8bits_cat.png) + +If you want a report of your memory-usage, run this [script](https://gist.github.com/sayakpaul/3ae0f847001d342af27018a96f467e4e). + + + +Text embeddings computed in 8-bit can impact the quality of the generated images because of the information loss in the representation space caused by the reduced precision. It's recommended to compare the outputs with and without 8-bit. + + + +While loading the `text_encoder`, you set `load_in_8bit` to `True`. You could also specify `load_in_4bit` to bring your memory requirements down even further to under 7GB. + +## PixArtSigmaPipeline + +[[autodoc]] PixArtSigmaPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/sana.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/sana.md new file mode 100644 index 0000000000000000000000000000000000000000..a66267c0948f3ad142f0289f7370ad802d351806 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/sana.md @@ -0,0 +1,112 @@ + + +# SanaPipeline + +
+ LoRA + MPS +
+ +[SANA: Efficient High-Resolution Image Synthesis with Linear Diffusion Transformers](https://huggingface.co/papers/2410.10629) from NVIDIA and MIT HAN Lab, by Enze Xie, Junsong Chen, Junyu Chen, Han Cai, Haotian Tang, Yujun Lin, Zhekai Zhang, Muyang Li, Ligeng Zhu, Yao Lu, Song Han. + +The abstract from the paper is: + +*We introduce Sana, a text-to-image framework that can efficiently generate images up to 4096×4096 resolution. Sana can synthesize high-resolution, high-quality images with strong text-image alignment at a remarkably fast speed, deployable on laptop GPU. Core designs include: (1) Deep compression autoencoder: unlike traditional AEs, which compress images only 8×, we trained an AE that can compress images 32×, effectively reducing the number of latent tokens. (2) Linear DiT: we replace all vanilla attention in DiT with linear attention, which is more efficient at high resolutions without sacrificing quality. (3) Decoder-only text encoder: we replaced T5 with modern decoder-only small LLM as the text encoder and designed complex human instruction with in-context learning to enhance the image-text alignment. (4) Efficient training and sampling: we propose Flow-DPM-Solver to reduce sampling steps, with efficient caption labeling and selection to accelerate convergence. As a result, Sana-0.6B is very competitive with modern giant diffusion model (e.g. Flux-12B), being 20 times smaller and 100+ times faster in measured throughput. Moreover, Sana-0.6B can be deployed on a 16GB laptop GPU, taking less than 1 second to generate a 1024×1024 resolution image. Sana enables content creation at low cost. Code and model will be publicly released.* + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +This pipeline was contributed by [lawrence-cj](https://github.com/lawrence-cj) and [chenjy2003](https://github.com/chenjy2003). The original codebase can be found [here](https://github.com/NVlabs/Sana). The original weights can be found under [hf.co/Efficient-Large-Model](https://huggingface.co/Efficient-Large-Model). + +Available models: + +| Model | Recommended dtype | +|:-----:|:-----------------:| +| [`Efficient-Large-Model/Sana_1600M_1024px_BF16_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_1024px_BF16_diffusers) | `torch.bfloat16` | +| [`Efficient-Large-Model/Sana_1600M_1024px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_1024px_diffusers) | `torch.float16` | +| [`Efficient-Large-Model/Sana_1600M_1024px_MultiLing_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_1024px_MultiLing_diffusers) | `torch.float16` | +| [`Efficient-Large-Model/Sana_1600M_512px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_512px_diffusers) | `torch.float16` | +| [`Efficient-Large-Model/Sana_1600M_512px_MultiLing_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_1600M_512px_MultiLing_diffusers) | `torch.float16` | +| [`Efficient-Large-Model/Sana_600M_1024px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_600M_1024px_diffusers) | `torch.float16` | +| [`Efficient-Large-Model/Sana_600M_512px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_600M_512px_diffusers) | `torch.float16` | + +Refer to [this](https://huggingface.co/collections/Efficient-Large-Model/sana-673efba2a57ed99843f11f9e) collection for more information. + +Note: The recommended dtype mentioned is for the transformer weights. The text encoder and VAE weights must stay in `torch.bfloat16` or `torch.float32` for the model to work correctly. Please refer to the inference example below to see how to load the model with the recommended dtype. + + + +Make sure to pass the `variant` argument for downloaded checkpoints to use lower disk space. Set it to `"fp16"` for models with recommended dtype as `torch.float16`, and `"bf16"` for models with recommended dtype as `torch.bfloat16`. By default, `torch.float32` weights are downloaded, which use twice the amount of disk storage. Additionally, `torch.float32` weights can be downcasted on-the-fly by specifying the `torch_dtype` argument. Read about it in the [docs](https://huggingface.co/docs/diffusers/v0.31.0/en/api/pipelines/overview#diffusers.DiffusionPipeline.from_pretrained). + + + +## Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`SanaPipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, SanaTransformer2DModel, SanaPipeline +from transformers import BitsAndBytesConfig as BitsAndBytesConfig, AutoModel + +quant_config = BitsAndBytesConfig(load_in_8bit=True) +text_encoder_8bit = AutoModel.from_pretrained( + "Efficient-Large-Model/Sana_1600M_1024px_diffusers", + subfolder="text_encoder", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = SanaTransformer2DModel.from_pretrained( + "Efficient-Large-Model/Sana_1600M_1024px_diffusers", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +pipeline = SanaPipeline.from_pretrained( + "Efficient-Large-Model/Sana_1600M_1024px_diffusers", + text_encoder=text_encoder_8bit, + transformer=transformer_8bit, + torch_dtype=torch.float16, + device_map="balanced", +) + +prompt = "a tiny astronaut hatching from an egg on the moon" +image = pipeline(prompt).images[0] +image.save("sana.png") +``` + +## SanaPipeline + +[[autodoc]] SanaPipeline + - all + - __call__ + +## SanaPAGPipeline + +[[autodoc]] SanaPAGPipeline + - all + - __call__ + +## SanaPipelineOutput + +[[autodoc]] pipelines.sana.pipeline_output.SanaPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/sana_sprint.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/sana_sprint.md new file mode 100644 index 0000000000000000000000000000000000000000..85a5b222205bc4e94c4974ead6164fcf89c11022 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/sana_sprint.md @@ -0,0 +1,134 @@ + + +# SANA-Sprint + +
+ LoRA +
+ +[SANA-Sprint: One-Step Diffusion with Continuous-Time Consistency Distillation](https://huggingface.co/papers/2503.09641) from NVIDIA, MIT HAN Lab, and Hugging Face by Junsong Chen, Shuchen Xue, Yuyang Zhao, Jincheng Yu, Sayak Paul, Junyu Chen, Han Cai, Enze Xie, Song Han + +The abstract from the paper is: + +*This paper presents SANA-Sprint, an efficient diffusion model for ultra-fast text-to-image (T2I) generation. SANA-Sprint is built on a pre-trained foundation model and augmented with hybrid distillation, dramatically reducing inference steps from 20 to 1-4. We introduce three key innovations: (1) We propose a training-free approach that transforms a pre-trained flow-matching model for continuous-time consistency distillation (sCM), eliminating costly training from scratch and achieving high training efficiency. Our hybrid distillation strategy combines sCM with latent adversarial distillation (LADD): sCM ensures alignment with the teacher model, while LADD enhances single-step generation fidelity. (2) SANA-Sprint is a unified step-adaptive model that achieves high-quality generation in 1-4 steps, eliminating step-specific training and improving efficiency. (3) We integrate ControlNet with SANA-Sprint for real-time interactive image generation, enabling instant visual feedback for user interaction. SANA-Sprint establishes a new Pareto frontier in speed-quality tradeoffs, achieving state-of-the-art performance with 7.59 FID and 0.74 GenEval in only 1 step — outperforming FLUX-schnell (7.94 FID / 0.71 GenEval) while being 10× faster (0.1s vs 1.1s on H100). It also achieves 0.1s (T2I) and 0.25s (ControlNet) latency for 1024×1024 images on H100, and 0.31s (T2I) on an RTX 4090, showcasing its exceptional efficiency and potential for AI-powered consumer applications (AIPC). Code and pre-trained models will be open-sourced.* + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +This pipeline was contributed by [lawrence-cj](https://github.com/lawrence-cj), [shuchen Xue](https://github.com/scxue) and [Enze Xie](https://github.com/xieenze). The original codebase can be found [here](https://github.com/NVlabs/Sana). The original weights can be found under [hf.co/Efficient-Large-Model](https://huggingface.co/Efficient-Large-Model/). + +Available models: + +| Model | Recommended dtype | +|:-------------------------------------------------------------------------------------------------------------------------------------------:|:-----------------:| +| [`Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers) | `torch.bfloat16` | +| [`Efficient-Large-Model/Sana_Sprint_0.6B_1024px_diffusers`](https://huggingface.co/Efficient-Large-Model/Sana_Sprint_0.6B_1024px_diffusers) | `torch.bfloat16` | + +Refer to [this](https://huggingface.co/collections/Efficient-Large-Model/sana-sprint-67d6810d65235085b3b17c76) collection for more information. + +Note: The recommended dtype mentioned is for the transformer weights. The text encoder must stay in `torch.bfloat16` and VAE weights must stay in `torch.bfloat16` or `torch.float32` for the model to work correctly. Please refer to the inference example below to see how to load the model with the recommended dtype. + + +## Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`SanaSprintPipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, SanaTransformer2DModel, SanaSprintPipeline +from transformers import BitsAndBytesConfig as BitsAndBytesConfig, AutoModel + +quant_config = BitsAndBytesConfig(load_in_8bit=True) +text_encoder_8bit = AutoModel.from_pretrained( + "Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers", + subfolder="text_encoder", + quantization_config=quant_config, + torch_dtype=torch.bfloat16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = SanaTransformer2DModel.from_pretrained( + "Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.bfloat16, +) + +pipeline = SanaSprintPipeline.from_pretrained( + "Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers", + text_encoder=text_encoder_8bit, + transformer=transformer_8bit, + torch_dtype=torch.bfloat16, + device_map="balanced", +) + +prompt = "a tiny astronaut hatching from an egg on the moon" +image = pipeline(prompt).images[0] +image.save("sana.png") +``` + +## Setting `max_timesteps` + +Users can tweak the `max_timesteps` value for experimenting with the visual quality of the generated outputs. The default `max_timesteps` value was obtained with an inference-time search process. For more details about it, check out the paper. + +## Image to Image + +The [`SanaSprintImg2ImgPipeline`] is a pipeline for image-to-image generation. It takes an input image and a prompt, and generates a new image based on the input image and the prompt. + +```py +import torch +from diffusers import SanaSprintImg2ImgPipeline +from diffusers.utils.loading_utils import load_image + +image = load_image( + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/penguin.png" +) + +pipe = SanaSprintImg2ImgPipeline.from_pretrained( + "Efficient-Large-Model/Sana_Sprint_1.6B_1024px_diffusers", + torch_dtype=torch.bfloat16) +pipe.to("cuda") + +image = pipe( + prompt="a cute pink bear", + image=image, + strength=0.5, + height=832, + width=480 +).images[0] +image[0].save("output.png") +``` + +## SanaSprintPipeline + +[[autodoc]] SanaSprintPipeline + - all + - __call__ + +## SanaSprintImg2ImgPipeline + +[[autodoc]] SanaSprintImg2ImgPipeline + - all + - __call__ + + +## SanaPipelineOutput + +[[autodoc]] pipelines.sana.pipeline_output.SanaPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/self_attention_guidance.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/self_attention_guidance.md new file mode 100644 index 0000000000000000000000000000000000000000..d656ce93f1047889db7d517e6d034deaa1226a8a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/self_attention_guidance.md @@ -0,0 +1,35 @@ + + +# Self-Attention Guidance + +[Improving Sample Quality of Diffusion Models Using Self-Attention Guidance](https://huggingface.co/papers/2210.00939) is by Susung Hong et al. + +The abstract from the paper is: + +*Denoising diffusion models (DDMs) have attracted attention for their exceptional generation quality and diversity. This success is largely attributed to the use of class- or text-conditional diffusion guidance methods, such as classifier and classifier-free guidance. In this paper, we present a more comprehensive perspective that goes beyond the traditional guidance methods. From this generalized perspective, we introduce novel condition- and training-free strategies to enhance the quality of generated images. As a simple solution, blur guidance improves the suitability of intermediate samples for their fine-scale information and structures, enabling diffusion models to generate higher quality samples with a moderate guidance scale. Improving upon this, Self-Attention Guidance (SAG) uses the intermediate self-attention maps of diffusion models to enhance their stability and efficacy. Specifically, SAG adversarially blurs only the regions that diffusion models attend to at each iteration and guides them accordingly. Our experimental results show that our SAG improves the performance of various diffusion models, including ADM, IDDPM, Stable Diffusion, and DiT. Moreover, combining SAG with conventional guidance methods leads to further improvement.* + +You can find additional information about Self-Attention Guidance on the [project page](https://ku-cvlab.github.io/Self-Attention-Guidance), [original codebase](https://github.com/KU-CVLAB/Self-Attention-Guidance), and try it out in a [demo](https://huggingface.co/spaces/susunghong/Self-Attention-Guidance) or [notebook](https://colab.research.google.com/github/SusungHong/Self-Attention-Guidance/blob/main/SAG_Stable.ipynb). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## StableDiffusionSAGPipeline +[[autodoc]] StableDiffusionSAGPipeline + - __call__ + - all + +## StableDiffusionOutput +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/semantic_stable_diffusion.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/semantic_stable_diffusion.md new file mode 100644 index 0000000000000000000000000000000000000000..b9aacd3518d8b084b5852bbf4b51cd21c4882ab3 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/semantic_stable_diffusion.md @@ -0,0 +1,35 @@ + + +# Semantic Guidance + +Semantic Guidance for Diffusion Models was proposed in [SEGA: Instructing Text-to-Image Models using Semantic Guidance](https://huggingface.co/papers/2301.12247) and provides strong semantic control over image generation. +Small changes to the text prompt usually result in entirely different output images. However, with SEGA a variety of changes to the image are enabled that can be controlled easily and intuitively, while staying true to the original image composition. + +The abstract from the paper is: + +*Text-to-image diffusion models have recently received a lot of interest for their astonishing ability to produce high-fidelity images from text only. However, achieving one-shot generation that aligns with the user's intent is nearly impossible, yet small changes to the input prompt often result in very different images. This leaves the user with little semantic control. To put the user in control, we show how to interact with the diffusion process to flexibly steer it along semantic directions. This semantic guidance (SEGA) generalizes to any generative architecture using classifier-free guidance. More importantly, it allows for subtle and extensive edits, changes in composition and style, as well as optimizing the overall artistic conception. We demonstrate SEGA's effectiveness on both latent and pixel-based diffusion models such as Stable Diffusion, Paella, and DeepFloyd-IF using a variety of tasks, thus providing strong evidence for its versatility, flexibility, and improvements over existing methods.* + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## SemanticStableDiffusionPipeline +[[autodoc]] SemanticStableDiffusionPipeline + - all + - __call__ + +## SemanticStableDiffusionPipelineOutput +[[autodoc]] pipelines.semantic_stable_diffusion.pipeline_output.SemanticStableDiffusionPipelineOutput + - all diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/shap_e.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/shap_e.md new file mode 100644 index 0000000000000000000000000000000000000000..3c1f939c1fce783eeddbe0ef0df8b93f36419d20 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/shap_e.md @@ -0,0 +1,37 @@ + + +# Shap-E + +The Shap-E model was proposed in [Shap-E: Generating Conditional 3D Implicit Functions](https://huggingface.co/papers/2305.02463) by Alex Nichol and Heewoo Jun from [OpenAI](https://github.com/openai). + +The abstract from the paper is: + +*We present Shap-E, a conditional generative model for 3D assets. Unlike recent work on 3D generative models which produce a single output representation, Shap-E directly generates the parameters of implicit functions that can be rendered as both textured meshes and neural radiance fields. We train Shap-E in two stages: first, we train an encoder that deterministically maps 3D assets into the parameters of an implicit function; second, we train a conditional diffusion model on outputs of the encoder. When trained on a large dataset of paired 3D and text data, our resulting models are capable of generating complex and diverse 3D assets in a matter of seconds. When compared to Point-E, an explicit generative model over point clouds, Shap-E converges faster and reaches comparable or better sample quality despite modeling a higher-dimensional, multi-representation output space.* + +The original codebase can be found at [openai/shap-e](https://github.com/openai/shap-e). + + + +See the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## ShapEPipeline +[[autodoc]] ShapEPipeline + - all + - __call__ + +## ShapEImg2ImgPipeline +[[autodoc]] ShapEImg2ImgPipeline + - all + - __call__ + +## ShapEPipelineOutput +[[autodoc]] pipelines.shap_e.pipeline_shap_e.ShapEPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_audio.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_audio.md new file mode 100644 index 0000000000000000000000000000000000000000..3f689ba0adeaacdc2577f0a886c17b8dd5fb35e1 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_audio.md @@ -0,0 +1,93 @@ + + +# Stable Audio + +Stable Audio was proposed in [Stable Audio Open](https://huggingface.co/papers/2407.14358) by Zach Evans et al. . it takes a text prompt as input and predicts the corresponding sound or music sample. + +Stable Audio Open generates variable-length (up to 47s) stereo audio at 44.1kHz from text prompts. It comprises three components: an autoencoder that compresses waveforms into a manageable sequence length, a T5-based text embedding for text conditioning, and a transformer-based diffusion (DiT) model that operates in the latent space of the autoencoder. + +Stable Audio is trained on a corpus of around 48k audio recordings, where around 47k are from Freesound and the rest are from the Free Music Archive (FMA). All audio files are licensed under CC0, CC BY, or CC Sampling+. This data is used to train the autoencoder and the DiT. + +The abstract of the paper is the following: +*Open generative models are vitally important for the community, allowing for fine-tunes and serving as baselines when presenting new models. However, most current text-to-audio models are private and not accessible for artists and researchers to build upon. Here we describe the architecture and training process of a new open-weights text-to-audio model trained with Creative Commons data. Our evaluation shows that the model's performance is competitive with the state-of-the-art across various metrics. Notably, the reported FDopenl3 results (measuring the realism of the generations) showcase its potential for high-quality stereo sound synthesis at 44.1kHz.* + +This pipeline was contributed by [Yoach Lacombe](https://huggingface.co/ylacombe). The original codebase can be found at [Stability-AI/stable-audio-tools](https://github.com/Stability-AI/stable-audio-tools). + +## Tips + +When constructing a prompt, keep in mind: + +* Descriptive prompt inputs work best; use adjectives to describe the sound (for example, "high quality" or "clear") and make the prompt context specific where possible (e.g. "melodic techno with a fast beat and synths" works better than "techno"). +* Using a *negative prompt* can significantly improve the quality of the generated audio. Try using a negative prompt of "low quality, average quality". + +During inference: + +* The _quality_ of the generated audio sample can be controlled by the `num_inference_steps` argument; higher steps give higher quality audio at the expense of slower inference. +* Multiple waveforms can be generated in one go: set `num_waveforms_per_prompt` to a value greater than 1 to enable. Automatic scoring will be performed between the generated waveforms and prompt text, and the audios ranked from best to worst accordingly. + +## Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`StableAudioPipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, StableAudioDiTModel, StableAudioPipeline +from diffusers.utils import export_to_video +from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel + +quant_config = BitsAndBytesConfig(load_in_8bit=True) +text_encoder_8bit = T5EncoderModel.from_pretrained( + "stabilityai/stable-audio-open-1.0", + subfolder="text_encoder", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = StableAudioDiTModel.from_pretrained( + "stabilityai/stable-audio-open-1.0", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +pipeline = StableAudioPipeline.from_pretrained( + "stabilityai/stable-audio-open-1.0", + text_encoder=text_encoder_8bit, + transformer=transformer_8bit, + torch_dtype=torch.float16, + device_map="balanced", +) + +prompt = "The sound of a hammer hitting a wooden surface." +negative_prompt = "Low quality." +audio = pipeline( + prompt, + negative_prompt=negative_prompt, + num_inference_steps=200, + audio_end_in_s=10.0, + num_waveforms_per_prompt=3, + generator=generator, +).audios + +output = audio[0].T.float().cpu().numpy() +sf.write("hammer.wav", output, pipeline.vae.sampling_rate) +``` + + +## StableAudioPipeline +[[autodoc]] StableAudioPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_cascade.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_cascade.md new file mode 100644 index 0000000000000000000000000000000000000000..93a94d66c1093bbf7efd295249d70acb6cb58624 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_cascade.md @@ -0,0 +1,229 @@ + + +# Stable Cascade + +This model is built upon the [Würstchen](https://openreview.net/forum?id=gU58d5QeGv) architecture and its main +difference to other models like Stable Diffusion is that it is working at a much smaller latent space. Why is this +important? The smaller the latent space, the **faster** you can run inference and the **cheaper** the training becomes. +How small is the latent space? Stable Diffusion uses a compression factor of 8, resulting in a 1024x1024 image being +encoded to 128x128. Stable Cascade achieves a compression factor of 42, meaning that it is possible to encode a +1024x1024 image to 24x24, while maintaining crisp reconstructions. The text-conditional model is then trained in the +highly compressed latent space. Previous versions of this architecture, achieved a 16x cost reduction over Stable +Diffusion 1.5. + +Therefore, this kind of model is well suited for usages where efficiency is important. Furthermore, all known extensions +like finetuning, LoRA, ControlNet, IP-Adapter, LCM etc. are possible with this method as well. + +The original codebase can be found at [Stability-AI/StableCascade](https://github.com/Stability-AI/StableCascade). + +## Model Overview +Stable Cascade consists of three models: Stage A, Stage B and Stage C, representing a cascade to generate images, +hence the name "Stable Cascade". + +Stage A & B are used to compress images, similar to what the job of the VAE is in Stable Diffusion. +However, with this setup, a much higher compression of images can be achieved. While the Stable Diffusion models use a +spatial compression factor of 8, encoding an image with resolution of 1024 x 1024 to 128 x 128, Stable Cascade achieves +a compression factor of 42. This encodes a 1024 x 1024 image to 24 x 24, while being able to accurately decode the +image. This comes with the great benefit of cheaper training and inference. Furthermore, Stage C is responsible +for generating the small 24 x 24 latents given a text prompt. + +The Stage C model operates on the small 24 x 24 latents and denoises the latents conditioned on text prompts. The model is also the largest component in the Cascade pipeline and is meant to be used with the `StableCascadePriorPipeline` + +The Stage B and Stage A models are used with the `StableCascadeDecoderPipeline` and are responsible for generating the final image given the small 24 x 24 latents. + + + +There are some restrictions on data types that can be used with the Stable Cascade models. The official checkpoints for the `StableCascadePriorPipeline` do not support the `torch.float16` data type. Please use `torch.bfloat16` instead. + +In order to use the `torch.bfloat16` data type with the `StableCascadeDecoderPipeline` you need to have PyTorch 2.2.0 or higher installed. This also means that using the `StableCascadeCombinedPipeline` with `torch.bfloat16` requires PyTorch 2.2.0 or higher, since it calls the `StableCascadeDecoderPipeline` internally. + +If it is not possible to install PyTorch 2.2.0 or higher in your environment, the `StableCascadeDecoderPipeline` can be used on its own with the `torch.float16` data type. You can download the full precision or `bf16` variant weights for the pipeline and cast the weights to `torch.float16`. + + + +## Usage example + +```python +import torch +from diffusers import StableCascadeDecoderPipeline, StableCascadePriorPipeline + +prompt = "an image of a shiba inu, donning a spacesuit and helmet" +negative_prompt = "" + +prior = StableCascadePriorPipeline.from_pretrained("stabilityai/stable-cascade-prior", variant="bf16", torch_dtype=torch.bfloat16) +decoder = StableCascadeDecoderPipeline.from_pretrained("stabilityai/stable-cascade", variant="bf16", torch_dtype=torch.float16) + +prior.enable_model_cpu_offload() +prior_output = prior( + prompt=prompt, + height=1024, + width=1024, + negative_prompt=negative_prompt, + guidance_scale=4.0, + num_images_per_prompt=1, + num_inference_steps=20 +) + +decoder.enable_model_cpu_offload() +decoder_output = decoder( + image_embeddings=prior_output.image_embeddings.to(torch.float16), + prompt=prompt, + negative_prompt=negative_prompt, + guidance_scale=0.0, + output_type="pil", + num_inference_steps=10 +).images[0] +decoder_output.save("cascade.png") +``` + +## Using the Lite Versions of the Stage B and Stage C models + +```python +import torch +from diffusers import ( + StableCascadeDecoderPipeline, + StableCascadePriorPipeline, + StableCascadeUNet, +) + +prompt = "an image of a shiba inu, donning a spacesuit and helmet" +negative_prompt = "" + +prior_unet = StableCascadeUNet.from_pretrained("stabilityai/stable-cascade-prior", subfolder="prior_lite") +decoder_unet = StableCascadeUNet.from_pretrained("stabilityai/stable-cascade", subfolder="decoder_lite") + +prior = StableCascadePriorPipeline.from_pretrained("stabilityai/stable-cascade-prior", prior=prior_unet) +decoder = StableCascadeDecoderPipeline.from_pretrained("stabilityai/stable-cascade", decoder=decoder_unet) + +prior.enable_model_cpu_offload() +prior_output = prior( + prompt=prompt, + height=1024, + width=1024, + negative_prompt=negative_prompt, + guidance_scale=4.0, + num_images_per_prompt=1, + num_inference_steps=20 +) + +decoder.enable_model_cpu_offload() +decoder_output = decoder( + image_embeddings=prior_output.image_embeddings, + prompt=prompt, + negative_prompt=negative_prompt, + guidance_scale=0.0, + output_type="pil", + num_inference_steps=10 +).images[0] +decoder_output.save("cascade.png") +``` + +## Loading original checkpoints with `from_single_file` + +Loading the original format checkpoints is supported via `from_single_file` method in the StableCascadeUNet. + +```python +import torch +from diffusers import ( + StableCascadeDecoderPipeline, + StableCascadePriorPipeline, + StableCascadeUNet, +) + +prompt = "an image of a shiba inu, donning a spacesuit and helmet" +negative_prompt = "" + +prior_unet = StableCascadeUNet.from_single_file( + "https://huggingface.co/stabilityai/stable-cascade/resolve/main/stage_c_bf16.safetensors", + torch_dtype=torch.bfloat16 +) +decoder_unet = StableCascadeUNet.from_single_file( + "https://huggingface.co/stabilityai/stable-cascade/blob/main/stage_b_bf16.safetensors", + torch_dtype=torch.bfloat16 +) + +prior = StableCascadePriorPipeline.from_pretrained("stabilityai/stable-cascade-prior", prior=prior_unet, torch_dtype=torch.bfloat16) +decoder = StableCascadeDecoderPipeline.from_pretrained("stabilityai/stable-cascade", decoder=decoder_unet, torch_dtype=torch.bfloat16) + +prior.enable_model_cpu_offload() +prior_output = prior( + prompt=prompt, + height=1024, + width=1024, + negative_prompt=negative_prompt, + guidance_scale=4.0, + num_images_per_prompt=1, + num_inference_steps=20 +) + +decoder.enable_model_cpu_offload() +decoder_output = decoder( + image_embeddings=prior_output.image_embeddings, + prompt=prompt, + negative_prompt=negative_prompt, + guidance_scale=0.0, + output_type="pil", + num_inference_steps=10 +).images[0] +decoder_output.save("cascade-single-file.png") +``` + +## Uses + +### Direct Use + +The model is intended for research purposes for now. Possible research areas and tasks include + +- Research on generative models. +- Safe deployment of models which have the potential to generate harmful content. +- Probing and understanding the limitations and biases of generative models. +- Generation of artworks and use in design and other artistic processes. +- Applications in educational or creative tools. + +Excluded uses are described below. + +### Out-of-Scope Use + +The model was not trained to be factual or true representations of people or events, +and therefore using the model to generate such content is out-of-scope for the abilities of this model. +The model should not be used in any way that violates Stability AI's [Acceptable Use Policy](https://stability.ai/use-policy). + +## Limitations and Bias + +### Limitations +- Faces and people in general may not be generated properly. +- The autoencoding part of the model is lossy. + + +## StableCascadeCombinedPipeline + +[[autodoc]] StableCascadeCombinedPipeline + - all + - __call__ + +## StableCascadePriorPipeline + +[[autodoc]] StableCascadePriorPipeline + - all + - __call__ + +## StableCascadePriorPipelineOutput + +[[autodoc]] pipelines.stable_cascade.pipeline_stable_cascade_prior.StableCascadePriorPipelineOutput + +## StableCascadeDecoderPipeline + +[[autodoc]] StableCascadeDecoderPipeline + - all + - __call__ + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/adapter.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/adapter.md new file mode 100644 index 0000000000000000000000000000000000000000..6a800f7881efd5c7a0e73154391dac1ce5b64b33 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/adapter.md @@ -0,0 +1,47 @@ + + +# T2I-Adapter + +[T2I-Adapter: Learning Adapters to Dig out More Controllable Ability for Text-to-Image Diffusion Models](https://huggingface.co/papers/2302.08453) by Chong Mou, Xintao Wang, Liangbin Xie, Jian Zhang, Zhongang Qi, Ying Shan, Xiaohu Qie. + +Using the pretrained models we can provide control images (for example, a depth map) to control Stable Diffusion text-to-image generation so that it follows the structure of the depth image and fills in the details. + +The abstract of the paper is the following: + +*The incredible generative ability of large-scale text-to-image (T2I) models has demonstrated strong power of learning complex structures and meaningful semantics. However, relying solely on text prompts cannot fully take advantage of the knowledge learned by the model, especially when flexible and accurate controlling (e.g., color and structure) is needed. In this paper, we aim to ``dig out" the capabilities that T2I models have implicitly learned, and then explicitly use them to control the generation more granularly. Specifically, we propose to learn simple and lightweight T2I-Adapters to align internal knowledge in T2I models with external control signals, while freezing the original large T2I models. In this way, we can train various adapters according to different conditions, achieving rich control and editing effects in the color and structure of the generation results. Further, the proposed T2I-Adapters have attractive properties of practical value, such as composability and generalization ability. Extensive experiments demonstrate that our T2I-Adapter has promising generation quality and a wide range of applications.* + +This model was contributed by the community contributor [HimariO](https://github.com/HimariO) ❤️ . + +## StableDiffusionAdapterPipeline + +[[autodoc]] StableDiffusionAdapterPipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_vae_slicing + - disable_vae_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + +## StableDiffusionXLAdapterPipeline + +[[autodoc]] StableDiffusionXLAdapterPipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_vae_slicing + - disable_vae_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/depth2img.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/depth2img.md new file mode 100644 index 0000000000000000000000000000000000000000..0cf58fe1d2fb5b09e0968f501459f60de1427ae5 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/depth2img.md @@ -0,0 +1,44 @@ + + +# Depth-to-image + +
+ LoRA +
+ +The Stable Diffusion model can also infer depth based on an image using [MiDaS](https://github.com/isl-org/MiDaS). This allows you to pass a text prompt and an initial image to condition the generation of new images as well as a `depth_map` to preserve the image structure. + + + +Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently! + +If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations! + + + +## StableDiffusionDepth2ImgPipeline + +[[autodoc]] StableDiffusionDepth2ImgPipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + - load_textual_inversion + - load_lora_weights + - save_lora_weights + +## StableDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/gligen.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/gligen.md new file mode 100644 index 0000000000000000000000000000000000000000..c67544472ead6fd89f67f013a0e92bbfb07d125b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/gligen.md @@ -0,0 +1,59 @@ + + +# GLIGEN (Grounded Language-to-Image Generation) + +The GLIGEN model was created by researchers and engineers from [University of Wisconsin-Madison, Columbia University, and Microsoft](https://github.com/gligen/GLIGEN). The [`StableDiffusionGLIGENPipeline`] and [`StableDiffusionGLIGENTextImagePipeline`] can generate photorealistic images conditioned on grounding inputs. Along with text and bounding boxes with [`StableDiffusionGLIGENPipeline`], if input images are given, [`StableDiffusionGLIGENTextImagePipeline`] can insert objects described by text at the region defined by bounding boxes. Otherwise, it'll generate an image described by the caption/prompt and insert objects described by text at the region defined by bounding boxes. It's trained on COCO2014D and COCO2014CD datasets, and the model uses a frozen CLIP ViT-L/14 text encoder to condition itself on grounding inputs. + +The abstract from the [paper](https://huggingface.co/papers/2301.07093) is: + +*Large-scale text-to-image diffusion models have made amazing advances. However, the status quo is to use text input alone, which can impede controllability. In this work, we propose GLIGEN, Grounded-Language-to-Image Generation, a novel approach that builds upon and extends the functionality of existing pre-trained text-to-image diffusion models by enabling them to also be conditioned on grounding inputs. To preserve the vast concept knowledge of the pre-trained model, we freeze all of its weights and inject the grounding information into new trainable layers via a gated mechanism. Our model achieves open-world grounded text2img generation with caption and bounding box condition inputs, and the grounding ability generalizes well to novel spatial configurations and concepts. GLIGEN’s zeroshot performance on COCO and LVIS outperforms existing supervised layout-to-image baselines by a large margin.* + + + +Make sure to check out the Stable Diffusion [Tips](https://huggingface.co/docs/diffusers/en/api/pipelines/stable_diffusion/overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality and how to reuse pipeline components efficiently! + +If you want to use one of the official checkpoints for a task, explore the [gligen](https://huggingface.co/gligen) Hub organizations! + + + +[`StableDiffusionGLIGENPipeline`] was contributed by [Nikhil Gajendrakumar](https://github.com/nikhil-masterful) and [`StableDiffusionGLIGENTextImagePipeline`] was contributed by [Nguyễn Công Tú Anh](https://github.com/tuanh123789). + +## StableDiffusionGLIGENPipeline + +[[autodoc]] StableDiffusionGLIGENPipeline + - all + - __call__ + - enable_vae_slicing + - disable_vae_slicing + - enable_vae_tiling + - disable_vae_tiling + - enable_model_cpu_offload + - prepare_latents + - enable_fuser + +## StableDiffusionGLIGENTextImagePipeline + +[[autodoc]] StableDiffusionGLIGENTextImagePipeline + - all + - __call__ + - enable_vae_slicing + - disable_vae_slicing + - enable_vae_tiling + - disable_vae_tiling + - enable_model_cpu_offload + - prepare_latents + - enable_fuser + +## StableDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/image_variation.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/image_variation.md new file mode 100644 index 0000000000000000000000000000000000000000..57dd2f0d5b396d271652805d1d86a49c58e3efe9 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/image_variation.md @@ -0,0 +1,37 @@ + + +# Image variation + +The Stable Diffusion model can also generate variations from an input image. It uses a fine-tuned version of a Stable Diffusion model by [Justin Pinkney](https://www.justinpinkney.com/) from [Lambda](https://lambdalabs.com/). + +The original codebase can be found at [LambdaLabsML/lambda-diffusers](https://github.com/LambdaLabsML/lambda-diffusers#stable-diffusion-image-variations) and additional official checkpoints for image variation can be found at [lambdalabs/sd-image-variations-diffusers](https://huggingface.co/lambdalabs/sd-image-variations-diffusers). + + + +Make sure to check out the Stable Diffusion [Tips](./overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently! + + + +## StableDiffusionImageVariationPipeline + +[[autodoc]] StableDiffusionImageVariationPipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + +## StableDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/img2img.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/img2img.md new file mode 100644 index 0000000000000000000000000000000000000000..f5779de1ee626c8f01ec5874233eeda41b2966ad --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/img2img.md @@ -0,0 +1,59 @@ + + +# Image-to-image + +
+ LoRA +
+ +The Stable Diffusion model can also be applied to image-to-image generation by passing a text prompt and an initial image to condition the generation of new images. + +The [`StableDiffusionImg2ImgPipeline`] uses the diffusion-denoising mechanism proposed in [SDEdit: Guided Image Synthesis and Editing with Stochastic Differential Equations](https://huggingface.co/papers/2108.01073) by Chenlin Meng, Yutong He, Yang Song, Jiaming Song, Jiajun Wu, Jun-Yan Zhu, Stefano Ermon. + +The abstract from the paper is: + +*Guided image synthesis enables everyday users to create and edit photo-realistic images with minimum effort. The key challenge is balancing faithfulness to the user input (e.g., hand-drawn colored strokes) and realism of the synthesized image. Existing GAN-based methods attempt to achieve such balance using either conditional GANs or GAN inversions, which are challenging and often require additional training data or loss functions for individual applications. To address these issues, we introduce a new image synthesis and editing method, Stochastic Differential Editing (SDEdit), based on a diffusion model generative prior, which synthesizes realistic images by iteratively denoising through a stochastic differential equation (SDE). Given an input image with user guide of any type, SDEdit first adds noise to the input, then subsequently denoises the resulting image through the SDE prior to increase its realism. SDEdit does not require task-specific training or inversions and can naturally achieve the balance between realism and faithfulness. SDEdit significantly outperforms state-of-the-art GAN-based methods by up to 98.09% on realism and 91.72% on overall satisfaction scores, according to a human perception study, on multiple tasks, including stroke-based image synthesis and editing as well as image compositing.* + + + +Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently! + + + +## StableDiffusionImg2ImgPipeline + +[[autodoc]] StableDiffusionImg2ImgPipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + - load_textual_inversion + - from_single_file + - load_lora_weights + - save_lora_weights + +## StableDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput + +## FlaxStableDiffusionImg2ImgPipeline + +[[autodoc]] FlaxStableDiffusionImg2ImgPipeline + - all + - __call__ + +## FlaxStableDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_diffusion.FlaxStableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/inpaint.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/inpaint.md new file mode 100644 index 0000000000000000000000000000000000000000..f75c9ca3dd0b84c9828e0b7825685806e6dd7de6 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/inpaint.md @@ -0,0 +1,61 @@ + + +# Inpainting + +
+ LoRA +
+ +The Stable Diffusion model can also be applied to inpainting which lets you edit specific parts of an image by providing a mask and a text prompt using Stable Diffusion. + +## Tips + +It is recommended to use this pipeline with checkpoints that have been specifically fine-tuned for inpainting, such +as [runwayml/stable-diffusion-inpainting](https://huggingface.co/runwayml/stable-diffusion-inpainting). Default +text-to-image Stable Diffusion checkpoints, such as +[stable-diffusion-v1-5/stable-diffusion-v1-5](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) are also compatible but they might be less performant. + + + +Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently! + +If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations! + + + +## StableDiffusionInpaintPipeline + +[[autodoc]] StableDiffusionInpaintPipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + - load_textual_inversion + - load_lora_weights + - save_lora_weights + +## StableDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput + +## FlaxStableDiffusionInpaintPipeline + +[[autodoc]] FlaxStableDiffusionInpaintPipeline + - all + - __call__ + +## FlaxStableDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_diffusion.FlaxStableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/k_diffusion.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/k_diffusion.md new file mode 100644 index 0000000000000000000000000000000000000000..77e77f8eded8ea4059f22c1d01cce9fa62a96752 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/k_diffusion.md @@ -0,0 +1,27 @@ + + +# K-Diffusion + +[k-diffusion](https://github.com/crowsonkb/k-diffusion) is a popular library created by [Katherine Crowson](https://github.com/crowsonkb/). We provide `StableDiffusionKDiffusionPipeline` and `StableDiffusionXLKDiffusionPipeline` that allow you to run Stable DIffusion with samplers from k-diffusion. + +Note that most the samplers from k-diffusion are implemented in Diffusers and we recommend using existing schedulers. You can find a mapping between k-diffusion samplers and schedulers in Diffusers [here](https://huggingface.co/docs/diffusers/api/schedulers/overview) + + +## StableDiffusionKDiffusionPipeline + +[[autodoc]] StableDiffusionKDiffusionPipeline + + +## StableDiffusionXLKDiffusionPipeline + +[[autodoc]] StableDiffusionXLKDiffusionPipeline \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/latent_upscale.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/latent_upscale.md new file mode 100644 index 0000000000000000000000000000000000000000..9abccd6e134713125914ca8080ee9195696fb8ed --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/latent_upscale.md @@ -0,0 +1,38 @@ + + +# Latent upscaler + +The Stable Diffusion latent upscaler model was created by [Katherine Crowson](https://github.com/crowsonkb/k-diffusion) in collaboration with [Stability AI](https://stability.ai/). It is used to enhance the output image resolution by a factor of 2 (see this demo [notebook](https://colab.research.google.com/drive/1o1qYJcFeywzCIdkfKJy7cTpgZTCM2EI4) for a demonstration of the original implementation). + + + +Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently! + +If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations! + + + +## StableDiffusionLatentUpscalePipeline + +[[autodoc]] StableDiffusionLatentUpscalePipeline + - all + - __call__ + - enable_sequential_cpu_offload + - enable_attention_slicing + - disable_attention_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + +## StableDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/ldm3d_diffusion.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/ldm3d_diffusion.md new file mode 100644 index 0000000000000000000000000000000000000000..e5ea487813b823db8d6753139302ec15b0b523c2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/ldm3d_diffusion.md @@ -0,0 +1,59 @@ + + +# Text-to-(RGB, depth) + +
+ LoRA +
+ +LDM3D was proposed in [LDM3D: Latent Diffusion Model for 3D](https://huggingface.co/papers/2305.10853) by Gabriela Ben Melech Stan, Diana Wofk, Scottie Fox, Alex Redden, Will Saxton, Jean Yu, Estelle Aflalo, Shao-Yen Tseng, Fabio Nonato, Matthias Muller, and Vasudev Lal. LDM3D generates an image and a depth map from a given text prompt unlike the existing text-to-image diffusion models such as [Stable Diffusion](./overview) which only generates an image. With almost the same number of parameters, LDM3D achieves to create a latent space that can compress both the RGB images and the depth maps. + +Two checkpoints are available for use: +- [ldm3d-original](https://huggingface.co/Intel/ldm3d). The original checkpoint used in the [paper](https://huggingface.co/papers/2305.10853) +- [ldm3d-4c](https://huggingface.co/Intel/ldm3d-4c). The new version of LDM3D using 4 channels inputs instead of 6-channels inputs and finetuned on higher resolution images. + + +The abstract from the paper is: + +*This research paper proposes a Latent Diffusion Model for 3D (LDM3D) that generates both image and depth map data from a given text prompt, allowing users to generate RGBD images from text prompts. The LDM3D model is fine-tuned on a dataset of tuples containing an RGB image, depth map and caption, and validated through extensive experiments. We also develop an application called DepthFusion, which uses the generated RGB images and depth maps to create immersive and interactive 360-degree-view experiences using TouchDesigner. This technology has the potential to transform a wide range of industries, from entertainment and gaming to architecture and design. Overall, this paper presents a significant contribution to the field of generative AI and computer vision, and showcases the potential of LDM3D and DepthFusion to revolutionize content creation and digital experiences. A short video summarizing the approach can be found at [this url](https://t.ly/tdi2).* + + + +Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently! + + + +## StableDiffusionLDM3DPipeline + +[[autodoc]] pipelines.stable_diffusion_ldm3d.pipeline_stable_diffusion_ldm3d.StableDiffusionLDM3DPipeline + - all + - __call__ + + +## LDM3DPipelineOutput + +[[autodoc]] pipelines.stable_diffusion_ldm3d.pipeline_stable_diffusion_ldm3d.LDM3DPipelineOutput + - all + - __call__ + +# Upscaler + +[LDM3D-VR](https://huggingface.co/papers/2311.03226) is an extended version of LDM3D. + +The abstract from the paper is: +*Latent diffusion models have proven to be state-of-the-art in the creation and manipulation of visual outputs. However, as far as we know, the generation of depth maps jointly with RGB is still limited. We introduce LDM3D-VR, a suite of diffusion models targeting virtual reality development that includes LDM3D-pano and LDM3D-SR. These models enable the generation of panoramic RGBD based on textual prompts and the upscaling of low-resolution inputs to high-resolution RGBD, respectively. Our models are fine-tuned from existing pretrained models on datasets containing panoramic/high-resolution RGB images, depth maps and captions. Both models are evaluated in comparison to existing related methods* + +Two checkpoints are available for use: +- [ldm3d-pano](https://huggingface.co/Intel/ldm3d-pano). This checkpoint enables the generation of panoramic images and requires the StableDiffusionLDM3DPipeline pipeline to be used. +- [ldm3d-sr](https://huggingface.co/Intel/ldm3d-sr). This checkpoint enables the upscaling of RGB and depth images. Can be used in cascade after the original LDM3D pipeline using the StableDiffusionUpscaleLDM3DPipeline from communauty pipeline. + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/overview.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/overview.md new file mode 100644 index 0000000000000000000000000000000000000000..25984091215c39cad34d1b8b27b875315b756c5e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/overview.md @@ -0,0 +1,216 @@ + + +# Stable Diffusion pipelines + +
+ LoRA +
+ +Stable Diffusion is a text-to-image latent diffusion model created by the researchers and engineers from [CompVis](https://github.com/CompVis), [Stability AI](https://stability.ai/) and [LAION](https://laion.ai/). Latent diffusion applies the diffusion process over a lower dimensional latent space to reduce memory and compute complexity. This specific type of diffusion model was proposed in [High-Resolution Image Synthesis with Latent Diffusion Models](https://huggingface.co/papers/2112.10752) by Robin Rombach, Andreas Blattmann, Dominik Lorenz, Patrick Esser, Björn Ommer. + +Stable Diffusion is trained on 512x512 images from a subset of the LAION-5B dataset. This model uses a frozen CLIP ViT-L/14 text encoder to condition the model on text prompts. With its 860M UNet and 123M text encoder, the model is relatively lightweight and can run on consumer GPUs. + +For more details about how Stable Diffusion works and how it differs from the base latent diffusion model, take a look at the Stability AI [announcement](https://stability.ai/blog/stable-diffusion-announcement) and our own [blog post](https://huggingface.co/blog/stable_diffusion#how-does-stable-diffusion-work) for more technical details. + +You can find the original codebase for Stable Diffusion v1.0 at [CompVis/stable-diffusion](https://github.com/CompVis/stable-diffusion) and Stable Diffusion v2.0 at [Stability-AI/stablediffusion](https://github.com/Stability-AI/stablediffusion) as well as their original scripts for various tasks. Additional official checkpoints for the different Stable Diffusion versions and tasks can be found on the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations. Explore these organizations to find the best checkpoint for your use-case! + +The table below summarizes the available Stable Diffusion pipelines, their supported tasks, and an interactive demo: + +
+
+ + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + +
+ Pipeline + + Supported tasks + + 🤗 Space +
+ StableDiffusion + text-to-image +
+ StableDiffusionImg2Img + image-to-image +
+ StableDiffusionInpaint + inpainting +
+ StableDiffusionDepth2Img + depth-to-image +
+ StableDiffusionImageVariation + image variation +
+ StableDiffusionPipelineSafe + filtered text-to-image +
+ StableDiffusion2 + text-to-image, inpainting, depth-to-image, super-resolution +
+ StableDiffusionXL + text-to-image, image-to-image +
+ StableDiffusionLatentUpscale + super-resolution +
+ StableDiffusionUpscale + super-resolution
+ StableDiffusionLDM3D + text-to-rgb, text-to-depth, text-to-pano +
+ StableDiffusionUpscaleLDM3D + ldm3d super-resolution
+
+
+ +## Tips + +To help you get the most out of the Stable Diffusion pipelines, here are a few tips for improving performance and usability. These tips are applicable to all Stable Diffusion pipelines. + +### Explore tradeoff between speed and quality + +[`StableDiffusionPipeline`] uses the [`PNDMScheduler`] by default, but 🤗 Diffusers provides many other schedulers (some of which are faster or output better quality) that are compatible. For example, if you want to use the [`EulerDiscreteScheduler`] instead of the default: + +```py +from diffusers import StableDiffusionPipeline, EulerDiscreteScheduler + +pipeline = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4") +pipeline.scheduler = EulerDiscreteScheduler.from_config(pipeline.scheduler.config) + +# or +euler_scheduler = EulerDiscreteScheduler.from_pretrained("CompVis/stable-diffusion-v1-4", subfolder="scheduler") +pipeline = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4", scheduler=euler_scheduler) +``` + +### Reuse pipeline components to save memory + +To save memory and use the same components across multiple pipelines, use the `.components` method to avoid loading weights into RAM more than once. + +```py +from diffusers import ( + StableDiffusionPipeline, + StableDiffusionImg2ImgPipeline, + StableDiffusionInpaintPipeline, +) + +text2img = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4") +img2img = StableDiffusionImg2ImgPipeline(**text2img.components) +inpaint = StableDiffusionInpaintPipeline(**text2img.components) + +# now you can use text2img(...), img2img(...), inpaint(...) just like the call methods of each respective pipeline +``` + +### Create web demos using `gradio` + +The Stable Diffusion pipelines are automatically supported in [Gradio](https://github.com/gradio-app/gradio/), a library that makes creating beautiful and user-friendly machine learning apps on the web a breeze. First, make sure you have Gradio installed: + +```sh +pip install -U gradio +``` + +Then, create a web demo around any Stable Diffusion-based pipeline. For example, you can create an image generation pipeline in a single line of code with Gradio's [`Interface.from_pipeline`](https://www.gradio.app/docs/interface#interface-from-pipeline) function: + +```py +from diffusers import StableDiffusionPipeline +import gradio as gr + +pipe = StableDiffusionPipeline.from_pretrained("CompVis/stable-diffusion-v1-4") + +gr.Interface.from_pipeline(pipe).launch() +``` + +which opens an intuitive drag-and-drop interface in your browser: + +![](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/gradio-panda.png) + +Similarly, you could create a demo for an image-to-image pipeline with: + +```py +from diffusers import StableDiffusionImg2ImgPipeline +import gradio as gr + + +pipe = StableDiffusionImg2ImgPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5") + +gr.Interface.from_pipeline(pipe).launch() +``` + +By default, the web demo runs on a local server. If you'd like to share it with others, you can generate a temporary public +link by setting `share=True` in `launch()`. Or, you can host your demo on [Hugging Face Spaces](https://huggingface.co/spaces)https://huggingface.co/spaces for a permanent link. \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/sdxl_turbo.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/sdxl_turbo.md new file mode 100644 index 0000000000000000000000000000000000000000..764685a73cfb3672f523a37263417defe2413848 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/sdxl_turbo.md @@ -0,0 +1,35 @@ + + +# SDXL Turbo + +Stable Diffusion XL (SDXL) Turbo was proposed in [Adversarial Diffusion Distillation](https://stability.ai/research/adversarial-diffusion-distillation) by Axel Sauer, Dominik Lorenz, Andreas Blattmann, and Robin Rombach. + +The abstract from the paper is: + +*We introduce Adversarial Diffusion Distillation (ADD), a novel training approach that efficiently samples large-scale foundational image diffusion models in just 1–4 steps while maintaining high image quality. We use score distillation to leverage large-scale off-the-shelf image diffusion models as a teacher signal in combination with an adversarial loss to ensure high image fidelity even in the low-step regime of one or two sampling steps. Our analyses show that our model clearly outperforms existing few-step methods (GANs,Latent Consistency Models) in a single step and reaches the performance of state-of-the-art diffusion models (SDXL) in only four steps. ADD is the first method to unlock single-step, real-time image synthesis with foundation models.* + +## Tips + +- SDXL Turbo uses the exact same architecture as [SDXL](./stable_diffusion_xl), which means it also has the same API. Please refer to the [SDXL](./stable_diffusion_xl) API reference for more details. +- SDXL Turbo should disable guidance scale by setting `guidance_scale=0.0`. +- SDXL Turbo should use `timestep_spacing='trailing'` for the scheduler and use between 1 and 4 steps. +- SDXL Turbo has been trained to generate images of size 512x512. +- SDXL Turbo is open-access, but not open-source meaning that one might have to buy a model license in order to use it for commercial applications. Make sure to read the [official model card](https://huggingface.co/stabilityai/sdxl-turbo) to learn more. + + + +To learn how to use SDXL Turbo for various tasks, how to optimize performance, and other usage examples, take a look at the [SDXL Turbo](../../../using-diffusers/sdxl_turbo) guide. + +Check out the [Stability AI](https://huggingface.co/stabilityai) Hub organization for the official base and refiner model checkpoints! + + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_2.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_2.md new file mode 100644 index 0000000000000000000000000000000000000000..a6bb50cc83d5805e567c82017281806cadd8ec98 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_2.md @@ -0,0 +1,125 @@ + + +# Stable Diffusion 2 + +Stable Diffusion 2 is a text-to-image _latent diffusion_ model built upon the work of the original [Stable Diffusion](https://stability.ai/blog/stable-diffusion-public-release), and it was led by Robin Rombach and Katherine Crowson from [Stability AI](https://stability.ai/) and [LAION](https://laion.ai/). + +*The Stable Diffusion 2.0 release includes robust text-to-image models trained using a brand new text encoder (OpenCLIP), developed by LAION with support from Stability AI, which greatly improves the quality of the generated images compared to earlier V1 releases. The text-to-image models in this release can generate images with default resolutions of both 512x512 pixels and 768x768 pixels. +These models are trained on an aesthetic subset of the [LAION-5B dataset](https://laion.ai/blog/laion-5b/) created by the DeepFloyd team at Stability AI, which is then further filtered to remove adult content using [LAION’s NSFW filter](https://openreview.net/forum?id=M3Y74vmsMcY).* + +For more details about how Stable Diffusion 2 works and how it differs from the original Stable Diffusion, please refer to the official [announcement post](https://stability.ai/blog/stable-diffusion-v2-release). + +The architecture of Stable Diffusion 2 is more or less identical to the original [Stable Diffusion model](./text2img) so check out it's API documentation for how to use Stable Diffusion 2. We recommend using the [`DPMSolverMultistepScheduler`] as it gives a reasonable speed/quality trade-off and can be run with as little as 20 steps. + +Stable Diffusion 2 is available for tasks like text-to-image, inpainting, super-resolution, and depth-to-image: + +| Task | Repository | +|-------------------------|---------------------------------------------------------------------------------------------------------------| +| text-to-image (512x512) | [stabilityai/stable-diffusion-2-base](https://huggingface.co/stabilityai/stable-diffusion-2-base) | +| text-to-image (768x768) | [stabilityai/stable-diffusion-2](https://huggingface.co/stabilityai/stable-diffusion-2) | +| inpainting | [stabilityai/stable-diffusion-2-inpainting](https://huggingface.co/stabilityai/stable-diffusion-2-inpainting) | +| super-resolution | [stable-diffusion-x4-upscaler](https://huggingface.co/stabilityai/stable-diffusion-x4-upscaler) | +| depth-to-image | [stabilityai/stable-diffusion-2-depth](https://huggingface.co/stabilityai/stable-diffusion-2-depth) | + +Here are some examples for how to use Stable Diffusion 2 for each task: + + + +Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently! + +If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations! + + + +## Text-to-image + +```py +from diffusers import DiffusionPipeline, DPMSolverMultistepScheduler +import torch + +repo_id = "stabilityai/stable-diffusion-2-base" +pipe = DiffusionPipeline.from_pretrained(repo_id, torch_dtype=torch.float16, variant="fp16") + +pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config) +pipe = pipe.to("cuda") + +prompt = "High quality photo of an astronaut riding a horse in space" +image = pipe(prompt, num_inference_steps=25).images[0] +image +``` + +## Inpainting + +```py +import torch +from diffusers import DiffusionPipeline, DPMSolverMultistepScheduler +from diffusers.utils import load_image, make_image_grid + +img_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo.png" +mask_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png" + +init_image = load_image(img_url).resize((512, 512)) +mask_image = load_image(mask_url).resize((512, 512)) + +repo_id = "stabilityai/stable-diffusion-2-inpainting" +pipe = DiffusionPipeline.from_pretrained(repo_id, torch_dtype=torch.float16, variant="fp16") + +pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config) +pipe = pipe.to("cuda") + +prompt = "Face of a yellow cat, high resolution, sitting on a park bench" +image = pipe(prompt=prompt, image=init_image, mask_image=mask_image, num_inference_steps=25).images[0] +make_image_grid([init_image, mask_image, image], rows=1, cols=3) +``` + +## Super-resolution + +```py +from diffusers import StableDiffusionUpscalePipeline +from diffusers.utils import load_image, make_image_grid +import torch + +# load model and scheduler +model_id = "stabilityai/stable-diffusion-x4-upscaler" +pipeline = StableDiffusionUpscalePipeline.from_pretrained(model_id, torch_dtype=torch.float16) +pipeline = pipeline.to("cuda") + +# let's download an image +url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/sd2-upscale/low_res_cat.png" +low_res_img = load_image(url) +low_res_img = low_res_img.resize((128, 128)) +prompt = "a white cat" +upscaled_image = pipeline(prompt=prompt, image=low_res_img).images[0] +make_image_grid([low_res_img.resize((512, 512)), upscaled_image.resize((512, 512))], rows=1, cols=2) +``` + +## Depth-to-image + +```py +import torch +from diffusers import StableDiffusionDepth2ImgPipeline +from diffusers.utils import load_image, make_image_grid + +pipe = StableDiffusionDepth2ImgPipeline.from_pretrained( + "stabilityai/stable-diffusion-2-depth", + torch_dtype=torch.float16, +).to("cuda") + + +url = "http://images.cocodataset.org/val2017/000000039769.jpg" +init_image = load_image(url) +prompt = "two tigers" +negative_prompt = "bad, deformed, ugly, bad anotomy" +image = pipe(prompt=prompt, image=init_image, negative_prompt=negative_prompt, strength=0.7).images[0] +make_image_grid([init_image, image], rows=1, cols=2) +``` diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_3.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_3.md new file mode 100644 index 0000000000000000000000000000000000000000..585af8d7074f6e6d70d68ca9c0e484792a512de7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_3.md @@ -0,0 +1,452 @@ + + +# Stable Diffusion 3 + +
+ LoRA + MPS +
+ +Stable Diffusion 3 (SD3) was proposed in [Scaling Rectified Flow Transformers for High-Resolution Image Synthesis](https://huggingface.co/papers/2403.03206) by Patrick Esser, Sumith Kulal, Andreas Blattmann, Rahim Entezari, Jonas Muller, Harry Saini, Yam Levi, Dominik Lorenz, Axel Sauer, Frederic Boesel, Dustin Podell, Tim Dockhorn, Zion English, Kyle Lacey, Alex Goodwin, Yannik Marek, and Robin Rombach. + +The abstract from the paper is: + +*Diffusion models create data from noise by inverting the forward paths of data towards noise and have emerged as a powerful generative modeling technique for high-dimensional, perceptual data such as images and videos. Rectified flow is a recent generative model formulation that connects data and noise in a straight line. Despite its better theoretical properties and conceptual simplicity, it is not yet decisively established as standard practice. In this work, we improve existing noise sampling techniques for training rectified flow models by biasing them towards perceptually relevant scales. Through a large-scale study, we demonstrate the superior performance of this approach compared to established diffusion formulations for high-resolution text-to-image synthesis. Additionally, we present a novel transformer-based architecture for text-to-image generation that uses separate weights for the two modalities and enables a bidirectional flow of information between image and text tokens, improving text comprehension typography, and human preference ratings. We demonstrate that this architecture follows predictable scaling trends and correlates lower validation loss to improved text-to-image synthesis as measured by various metrics and human evaluations.* + + +## Usage Example + +_As the model is gated, before using it with diffusers you first need to go to the [Stable Diffusion 3 Medium Hugging Face page](https://huggingface.co/stabilityai/stable-diffusion-3-medium-diffusers), fill in the form and accept the gate. Once you are in, you need to login so that your system knows you’ve accepted the gate._ + +Use the command below to log in: + +```bash +huggingface-cli login +``` + + + +The SD3 pipeline uses three text encoders to generate an image. Model offloading is necessary in order for it to run on most commodity hardware. Please use the `torch.float16` data type for additional memory savings. + + + +```python +import torch +from diffusers import StableDiffusion3Pipeline + +pipe = StableDiffusion3Pipeline.from_pretrained("stabilityai/stable-diffusion-3-medium-diffusers", torch_dtype=torch.float16) +pipe.to("cuda") + +image = pipe( + prompt="a photo of a cat holding a sign that says hello world", + negative_prompt="", + num_inference_steps=28, + height=1024, + width=1024, + guidance_scale=7.0, +).images[0] + +image.save("sd3_hello_world.png") +``` + +**Note:** Stable Diffusion 3.5 can also be run using the SD3 pipeline, and all mentioned optimizations and techniques apply to it as well. In total there are three official models in the SD3 family: +- [`stabilityai/stable-diffusion-3-medium-diffusers`](https://huggingface.co/stabilityai/stable-diffusion-3-medium-diffusers) +- [`stabilityai/stable-diffusion-3.5-large`](https://huggingface.co/stabilityai/stable-diffusion-3-5-large) +- [`stabilityai/stable-diffusion-3.5-large-turbo`](https://huggingface.co/stabilityai/stable-diffusion-3-5-large-turbo) + +## Image Prompting with IP-Adapters + +An IP-Adapter lets you prompt SD3 with images, in addition to the text prompt. This is especially useful when describing complex concepts that are difficult to articulate through text alone and you have reference images. To load and use an IP-Adapter, you need: + +- `image_encoder`: Pre-trained vision model used to obtain image features, usually a CLIP image encoder. +- `feature_extractor`: Image processor that prepares the input image for the chosen `image_encoder`. +- `ip_adapter_id`: Checkpoint containing parameters of image cross attention layers and image projection. + +IP-Adapters are trained for a specific model architecture, so they also work in finetuned variations of the base model. You can use the [`~SD3IPAdapterMixin.set_ip_adapter_scale`] function to adjust how strongly the output aligns with the image prompt. The higher the value, the more closely the model follows the image prompt. A default value of 0.5 is typically a good balance, ensuring the model considers both the text and image prompts equally. + +```python +import torch +from PIL import Image + +from diffusers import StableDiffusion3Pipeline +from transformers import SiglipVisionModel, SiglipImageProcessor + +image_encoder_id = "google/siglip-so400m-patch14-384" +ip_adapter_id = "InstantX/SD3.5-Large-IP-Adapter" + +feature_extractor = SiglipImageProcessor.from_pretrained( + image_encoder_id, + torch_dtype=torch.float16 +) +image_encoder = SiglipVisionModel.from_pretrained( + image_encoder_id, + torch_dtype=torch.float16 +).to( "cuda") + +pipe = StableDiffusion3Pipeline.from_pretrained( + "stabilityai/stable-diffusion-3.5-large", + torch_dtype=torch.float16, + feature_extractor=feature_extractor, + image_encoder=image_encoder, +).to("cuda") + +pipe.load_ip_adapter(ip_adapter_id) +pipe.set_ip_adapter_scale(0.6) + +ref_img = Image.open("image.jpg").convert('RGB') + +image = pipe( + width=1024, + height=1024, + prompt="a cat", + negative_prompt="lowres, low quality, worst quality", + num_inference_steps=24, + guidance_scale=5.0, + ip_adapter_image=ref_img +).images[0] + +image.save("result.jpg") +``` + +
+ +
IP-Adapter examples with prompt "a cat"
+
+ + + + +Check out [IP-Adapter](../../../using-diffusers/ip_adapter) to learn more about how IP-Adapters work. + + + + +## Memory Optimisations for SD3 + +SD3 uses three text encoders, one of which is the very large T5-XXL model. This makes it challenging to run the model on GPUs with less than 24GB of VRAM, even when using `fp16` precision. The following section outlines a few memory optimizations in Diffusers that make it easier to run SD3 on low resource hardware. + +### Running Inference with Model Offloading + +The most basic memory optimization available in Diffusers allows you to offload the components of the model to CPU during inference in order to save memory, while seeing a slight increase in inference latency. Model offloading will only move a model component onto the GPU when it needs to be executed, while keeping the remaining components on the CPU. + +```python +import torch +from diffusers import StableDiffusion3Pipeline + +pipe = StableDiffusion3Pipeline.from_pretrained("stabilityai/stable-diffusion-3-medium-diffusers", torch_dtype=torch.float16) +pipe.enable_model_cpu_offload() + +image = pipe( + prompt="a photo of a cat holding a sign that says hello world", + negative_prompt="", + num_inference_steps=28, + height=1024, + width=1024, + guidance_scale=7.0, +).images[0] + +image.save("sd3_hello_world.png") +``` + +### Dropping the T5 Text Encoder during Inference + +Removing the memory-intensive 4.7B parameter T5-XXL text encoder during inference can significantly decrease the memory requirements for SD3 with only a slight loss in performance. + +```python +import torch +from diffusers import StableDiffusion3Pipeline + +pipe = StableDiffusion3Pipeline.from_pretrained( + "stabilityai/stable-diffusion-3-medium-diffusers", + text_encoder_3=None, + tokenizer_3=None, + torch_dtype=torch.float16 +) +pipe.to("cuda") + +image = pipe( + prompt="a photo of a cat holding a sign that says hello world", + negative_prompt="", + num_inference_steps=28, + height=1024, + width=1024, + guidance_scale=7.0, +).images[0] + +image.save("sd3_hello_world-no-T5.png") +``` + +### Using a Quantized Version of the T5 Text Encoder + +We can leverage the `bitsandbytes` library to load and quantize the T5-XXL text encoder to 8-bit precision. This allows you to keep using all three text encoders while only slightly impacting performance. + +First install the `bitsandbytes` library. + +```shell +pip install bitsandbytes +``` + +Then load the T5-XXL model using the `BitsAndBytesConfig`. + +```python +import torch +from diffusers import StableDiffusion3Pipeline +from transformers import T5EncoderModel, BitsAndBytesConfig + +quantization_config = BitsAndBytesConfig(load_in_8bit=True) + +model_id = "stabilityai/stable-diffusion-3-medium-diffusers" +text_encoder = T5EncoderModel.from_pretrained( + model_id, + subfolder="text_encoder_3", + quantization_config=quantization_config, +) +pipe = StableDiffusion3Pipeline.from_pretrained( + model_id, + text_encoder_3=text_encoder, + device_map="balanced", + torch_dtype=torch.float16 +) + +image = pipe( + prompt="a photo of a cat holding a sign that says hello world", + negative_prompt="", + num_inference_steps=28, + height=1024, + width=1024, + guidance_scale=7.0, +).images[0] + +image.save("sd3_hello_world-8bit-T5.png") +``` + +You can find the end-to-end script [here](https://gist.github.com/sayakpaul/82acb5976509851f2db1a83456e504f1). + +## Performance Optimizations for SD3 + +### Using Torch Compile to Speed Up Inference + +Using compiled components in the SD3 pipeline can speed up inference by as much as 4X. The following code snippet demonstrates how to compile the Transformer and VAE components of the SD3 pipeline. + +```python +import torch +from diffusers import StableDiffusion3Pipeline + +torch.set_float32_matmul_precision("high") + +torch._inductor.config.conv_1x1_as_mm = True +torch._inductor.config.coordinate_descent_tuning = True +torch._inductor.config.epilogue_fusion = False +torch._inductor.config.coordinate_descent_check_all_directions = True + +pipe = StableDiffusion3Pipeline.from_pretrained( + "stabilityai/stable-diffusion-3-medium-diffusers", + torch_dtype=torch.float16 +).to("cuda") +pipe.set_progress_bar_config(disable=True) + +pipe.transformer.to(memory_format=torch.channels_last) +pipe.vae.to(memory_format=torch.channels_last) + +pipe.transformer = torch.compile(pipe.transformer, mode="max-autotune", fullgraph=True) +pipe.vae.decode = torch.compile(pipe.vae.decode, mode="max-autotune", fullgraph=True) + +# Warm Up +prompt = "a photo of a cat holding a sign that says hello world" +for _ in range(3): + _ = pipe(prompt=prompt, generator=torch.manual_seed(1)) + +# Run Inference +image = pipe(prompt=prompt, generator=torch.manual_seed(1)).images[0] +image.save("sd3_hello_world.png") +``` + +Check out the full script [here](https://gist.github.com/sayakpaul/508d89d7aad4f454900813da5d42ca97). + +## Quantization + +Quantization helps reduce the memory requirements of very large models by storing model weights in a lower precision data type. However, quantization may have varying impact on video quality depending on the video model. + +Refer to the [Quantization](../../quantization/overview) overview to learn more about supported quantization backends and selecting a quantization backend that supports your use case. The example below demonstrates how to load a quantized [`StableDiffusion3Pipeline`] for inference with bitsandbytes. + +```py +import torch +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig, SD3Transformer2DModel, StableDiffusion3Pipeline +from transformers import BitsAndBytesConfig as BitsAndBytesConfig, T5EncoderModel + +quant_config = BitsAndBytesConfig(load_in_8bit=True) +text_encoder_8bit = T5EncoderModel.from_pretrained( + "stabilityai/stable-diffusion-3.5-large", + subfolder="text_encoder_3", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True) +transformer_8bit = SD3Transformer2DModel.from_pretrained( + "stabilityai/stable-diffusion-3.5-large", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +pipeline = StableDiffusion3Pipeline.from_pretrained( + "stabilityai/stable-diffusion-3.5-large", + text_encoder=text_encoder_8bit, + transformer=transformer_8bit, + torch_dtype=torch.float16, + device_map="balanced", +) + +prompt = "a tiny astronaut hatching from an egg on the moon" +image = pipeline(prompt, num_inference_steps=28, guidance_scale=7.0).images[0] +image.save("sd3.png") +``` + +## Using Long Prompts with the T5 Text Encoder + +By default, the T5 Text Encoder prompt uses a maximum sequence length of `256`. This can be adjusted by setting the `max_sequence_length` to accept fewer or more tokens. Keep in mind that longer sequences require additional resources and result in longer generation times, such as during batch inference. + +```python +prompt = "A whimsical and creative image depicting a hybrid creature that is a mix of a waffle and a hippopotamus, basking in a river of melted butter amidst a breakfast-themed landscape. It features the distinctive, bulky body shape of a hippo. However, instead of the usual grey skin, the creature’s body resembles a golden-brown, crispy waffle fresh off the griddle. The skin is textured with the familiar grid pattern of a waffle, each square filled with a glistening sheen of syrup. The environment combines the natural habitat of a hippo with elements of a breakfast table setting, a river of warm, melted butter, with oversized utensils or plates peeking out from the lush, pancake-like foliage in the background, a towering pepper mill standing in for a tree. As the sun rises in this fantastical world, it casts a warm, buttery glow over the scene. The creature, content in its butter river, lets out a yawn. Nearby, a flock of birds take flight" + +image = pipe( + prompt=prompt, + negative_prompt="", + num_inference_steps=28, + guidance_scale=4.5, + max_sequence_length=512, +).images[0] +``` + +### Sending a different prompt to the T5 Text Encoder + +You can send a different prompt to the CLIP Text Encoders and the T5 Text Encoder to prevent the prompt from being truncated by the CLIP Text Encoders and to improve generation. + + + +The prompt with the CLIP Text Encoders is still truncated to the 77 token limit. + + + +```python +prompt = "A whimsical and creative image depicting a hybrid creature that is a mix of a waffle and a hippopotamus, basking in a river of melted butter amidst a breakfast-themed landscape. A river of warm, melted butter, pancake-like foliage in the background, a towering pepper mill standing in for a tree." + +prompt_3 = "A whimsical and creative image depicting a hybrid creature that is a mix of a waffle and a hippopotamus, basking in a river of melted butter amidst a breakfast-themed landscape. It features the distinctive, bulky body shape of a hippo. However, instead of the usual grey skin, the creature’s body resembles a golden-brown, crispy waffle fresh off the griddle. The skin is textured with the familiar grid pattern of a waffle, each square filled with a glistening sheen of syrup. The environment combines the natural habitat of a hippo with elements of a breakfast table setting, a river of warm, melted butter, with oversized utensils or plates peeking out from the lush, pancake-like foliage in the background, a towering pepper mill standing in for a tree. As the sun rises in this fantastical world, it casts a warm, buttery glow over the scene. The creature, content in its butter river, lets out a yawn. Nearby, a flock of birds take flight" + +image = pipe( + prompt=prompt, + prompt_3=prompt_3, + negative_prompt="", + num_inference_steps=28, + guidance_scale=4.5, + max_sequence_length=512, +).images[0] +``` + +## Tiny AutoEncoder for Stable Diffusion 3 + +Tiny AutoEncoder for Stable Diffusion (TAESD3) is a tiny distilled version of Stable Diffusion 3's VAE by [Ollin Boer Bohan](https://github.com/madebyollin/taesd) that can decode [`StableDiffusion3Pipeline`] latents almost instantly. + +To use with Stable Diffusion 3: + +```python +import torch +from diffusers import StableDiffusion3Pipeline, AutoencoderTiny + +pipe = StableDiffusion3Pipeline.from_pretrained( + "stabilityai/stable-diffusion-3-medium-diffusers", torch_dtype=torch.float16 +) +pipe.vae = AutoencoderTiny.from_pretrained("madebyollin/taesd3", torch_dtype=torch.float16) +pipe = pipe.to("cuda") + +prompt = "slice of delicious New York-style berry cheesecake" +image = pipe(prompt, num_inference_steps=25).images[0] +image.save("cheesecake.png") +``` + +## Loading the original checkpoints via `from_single_file` + +The `SD3Transformer2DModel` and `StableDiffusion3Pipeline` classes support loading the original checkpoints via the `from_single_file` method. This method allows you to load the original checkpoint files that were used to train the models. + +## Loading the original checkpoints for the `SD3Transformer2DModel` + +```python +from diffusers import SD3Transformer2DModel + +model = SD3Transformer2DModel.from_single_file("https://huggingface.co/stabilityai/stable-diffusion-3-medium/blob/main/sd3_medium.safetensors") +``` + +## Loading the single checkpoint for the `StableDiffusion3Pipeline` + +### Loading the single file checkpoint without T5 + +```python +import torch +from diffusers import StableDiffusion3Pipeline + +pipe = StableDiffusion3Pipeline.from_single_file( + "https://huggingface.co/stabilityai/stable-diffusion-3-medium/blob/main/sd3_medium_incl_clips.safetensors", + torch_dtype=torch.float16, + text_encoder_3=None +) +pipe.enable_model_cpu_offload() + +image = pipe("a picture of a cat holding a sign that says hello world").images[0] +image.save('sd3-single-file.png') +``` + +### Loading the single file checkpoint with T5 + +> [!TIP] +> The following example loads a checkpoint stored in a 8-bit floating point format which requires PyTorch 2.3 or later. + +```python +import torch +from diffusers import StableDiffusion3Pipeline + +pipe = StableDiffusion3Pipeline.from_single_file( + "https://huggingface.co/stabilityai/stable-diffusion-3-medium/blob/main/sd3_medium_incl_clips_t5xxlfp8.safetensors", + torch_dtype=torch.float16, +) +pipe.enable_model_cpu_offload() + +image = pipe("a picture of a cat holding a sign that says hello world").images[0] +image.save('sd3-single-file-t5-fp8.png') +``` + +### Loading the single file checkpoint for the Stable Diffusion 3.5 Transformer Model + +```python +import torch +from diffusers import SD3Transformer2DModel, StableDiffusion3Pipeline + +transformer = SD3Transformer2DModel.from_single_file( + "https://huggingface.co/stabilityai/stable-diffusion-3.5-large-turbo/blob/main/sd3.5_large.safetensors", + torch_dtype=torch.bfloat16, +) +pipe = StableDiffusion3Pipeline.from_pretrained( + "stabilityai/stable-diffusion-3.5-large", + transformer=transformer, + torch_dtype=torch.bfloat16, +) +pipe.enable_model_cpu_offload() +image = pipe("a cat holding a sign that says hello world").images[0] +image.save("sd35.png") +``` + +## StableDiffusion3Pipeline + +[[autodoc]] StableDiffusion3Pipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_safe.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_safe.md new file mode 100644 index 0000000000000000000000000000000000000000..97c11bfe23bb66c8733d18abb40850a6a3de0c2d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_safe.md @@ -0,0 +1,61 @@ + + +# Safe Stable Diffusion + +Safe Stable Diffusion was proposed in [Safe Latent Diffusion: Mitigating Inappropriate Degeneration in Diffusion Models](https://huggingface.co/papers/2211.05105) and mitigates inappropriate degeneration from Stable Diffusion models because they're trained on unfiltered web-crawled datasets. For instance Stable Diffusion may unexpectedly generate nudity, violence, images depicting self-harm, and otherwise offensive content. Safe Stable Diffusion is an extension of Stable Diffusion that drastically reduces this type of content. + +The abstract from the paper is: + +*Text-conditioned image generation models have recently achieved astonishing results in image quality and text alignment and are consequently employed in a fast-growing number of applications. Since they are highly data-driven, relying on billion-sized datasets randomly scraped from the internet, they also suffer, as we demonstrate, from degenerated and biased human behavior. In turn, they may even reinforce such biases. To help combat these undesired side effects, we present safe latent diffusion (SLD). Specifically, to measure the inappropriate degeneration due to unfiltered and imbalanced training sets, we establish a novel image generation test bed-inappropriate image prompts (I2P)-containing dedicated, real-world image-to-text prompts covering concepts such as nudity and violence. As our exhaustive empirical evaluation demonstrates, the introduced SLD removes and suppresses inappropriate image parts during the diffusion process, with no additional training required and no adverse effect on overall image quality or text alignment.* + +## Tips + +Use the `safety_concept` property of [`StableDiffusionPipelineSafe`] to check and edit the current safety concept: + +```python +>>> from diffusers import StableDiffusionPipelineSafe + +>>> pipeline = StableDiffusionPipelineSafe.from_pretrained("AIML-TUDA/stable-diffusion-safe") +>>> pipeline.safety_concept +'an image showing hate, harassment, violence, suffering, humiliation, harm, suicide, sexual, nudity, bodily fluids, blood, obscene gestures, illegal activity, drug use, theft, vandalism, weapons, child abuse, brutality, cruelty' +``` +For each image generation the active concept is also contained in [`StableDiffusionSafePipelineOutput`]. + +There are 4 configurations (`SafetyConfig.WEAK`, `SafetyConfig.MEDIUM`, `SafetyConfig.STRONG`, and `SafetyConfig.MAX`) that can be applied: + +```python +>>> from diffusers import StableDiffusionPipelineSafe +>>> from diffusers.pipelines.stable_diffusion_safe import SafetyConfig + +>>> pipeline = StableDiffusionPipelineSafe.from_pretrained("AIML-TUDA/stable-diffusion-safe") +>>> prompt = "the four horsewomen of the apocalypse, painting by tom of finland, gaston bussiere, craig mullins, j. c. leyendecker" +>>> out = pipeline(prompt=prompt, **SafetyConfig.MAX) +``` + + + +Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently! + + + +## StableDiffusionPipelineSafe + +[[autodoc]] StableDiffusionPipelineSafe + - all + - __call__ + +## StableDiffusionSafePipelineOutput + +[[autodoc]] pipelines.stable_diffusion_safe.StableDiffusionSafePipelineOutput + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_xl.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_xl.md new file mode 100644 index 0000000000000000000000000000000000000000..bf7ce9d793efff10f7a02ee8cdeeaadac9104648 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/stable_diffusion_xl.md @@ -0,0 +1,60 @@ + + +# Stable Diffusion XL + +
+ LoRA + MPS +
+ +Stable Diffusion XL (SDXL) was proposed in [SDXL: Improving Latent Diffusion Models for High-Resolution Image Synthesis](https://huggingface.co/papers/2307.01952) by Dustin Podell, Zion English, Kyle Lacey, Andreas Blattmann, Tim Dockhorn, Jonas Müller, Joe Penna, and Robin Rombach. + +The abstract from the paper is: + +*We present SDXL, a latent diffusion model for text-to-image synthesis. Compared to previous versions of Stable Diffusion, SDXL leverages a three times larger UNet backbone: The increase of model parameters is mainly due to more attention blocks and a larger cross-attention context as SDXL uses a second text encoder. We design multiple novel conditioning schemes and train SDXL on multiple aspect ratios. We also introduce a refinement model which is used to improve the visual fidelity of samples generated by SDXL using a post-hoc image-to-image technique. We demonstrate that SDXL shows drastically improved performance compared the previous versions of Stable Diffusion and achieves results competitive with those of black-box state-of-the-art image generators.* + +## Tips + +- Using SDXL with a DPM++ scheduler for less than 50 steps is known to produce [visual artifacts](https://github.com/huggingface/diffusers/issues/5433) because the solver becomes numerically unstable. To fix this issue, take a look at this [PR](https://github.com/huggingface/diffusers/pull/5541) which recommends for ODE/SDE solvers: + - set `use_karras_sigmas=True` or `lu_lambdas=True` to improve image quality + - set `euler_at_final=True` if you're using a solver with uniform step sizes (DPM++2M or DPM++2M SDE) +- Most SDXL checkpoints work best with an image size of 1024x1024. Image sizes of 768x768 and 512x512 are also supported, but the results aren't as good. Anything below 512x512 is not recommended and likely won't be for default checkpoints like [stabilityai/stable-diffusion-xl-base-1.0](https://huggingface.co/stabilityai/stable-diffusion-xl-base-1.0). +- SDXL can pass a different prompt for each of the text encoders it was trained on. We can even pass different parts of the same prompt to the text encoders. +- SDXL output images can be improved by making use of a refiner model in an image-to-image setting. +- SDXL offers `negative_original_size`, `negative_crops_coords_top_left`, and `negative_target_size` to negatively condition the model on image resolution and cropping parameters. + + + +To learn how to use SDXL for various tasks, how to optimize performance, and other usage examples, take a look at the [Stable Diffusion XL](../../../using-diffusers/sdxl) guide. + +Check out the [Stability AI](https://huggingface.co/stabilityai) Hub organization for the official base and refiner model checkpoints! + + + +## StableDiffusionXLPipeline + +[[autodoc]] StableDiffusionXLPipeline + - all + - __call__ + +## StableDiffusionXLImg2ImgPipeline + +[[autodoc]] StableDiffusionXLImg2ImgPipeline + - all + - __call__ + +## StableDiffusionXLInpaintPipeline + +[[autodoc]] StableDiffusionXLInpaintPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/svd.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/svd.md new file mode 100644 index 0000000000000000000000000000000000000000..87a9c2a5be869acc0820a30f99b62f8855daa2bb --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/svd.md @@ -0,0 +1,43 @@ + + +# Stable Video Diffusion + +Stable Video Diffusion was proposed in [Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets](https://hf.co/papers/2311.15127) by Andreas Blattmann, Tim Dockhorn, Sumith Kulal, Daniel Mendelevitch, Maciej Kilian, Dominik Lorenz, Yam Levi, Zion English, Vikram Voleti, Adam Letts, Varun Jampani, Robin Rombach. + +The abstract from the paper is: + +*We present Stable Video Diffusion - a latent video diffusion model for high-resolution, state-of-the-art text-to-video and image-to-video generation. Recently, latent diffusion models trained for 2D image synthesis have been turned into generative video models by inserting temporal layers and finetuning them on small, high-quality video datasets. However, training methods in the literature vary widely, and the field has yet to agree on a unified strategy for curating video data. In this paper, we identify and evaluate three different stages for successful training of video LDMs: text-to-image pretraining, video pretraining, and high-quality video finetuning. Furthermore, we demonstrate the necessity of a well-curated pretraining dataset for generating high-quality videos and present a systematic curation process to train a strong base model, including captioning and filtering strategies. We then explore the impact of finetuning our base model on high-quality data and train a text-to-video model that is competitive with closed-source video generation. We also show that our base model provides a powerful motion representation for downstream tasks such as image-to-video generation and adaptability to camera motion-specific LoRA modules. Finally, we demonstrate that our model provides a strong multi-view 3D-prior and can serve as a base to finetune a multi-view diffusion model that jointly generates multiple views of objects in a feedforward fashion, outperforming image-based methods at a fraction of their compute budget. We release code and model weights at this https URL.* + + + +To learn how to use Stable Video Diffusion, take a look at the [Stable Video Diffusion](../../../using-diffusers/svd) guide. + +
+ +Check out the [Stability AI](https://huggingface.co/stabilityai) Hub organization for the [base](https://huggingface.co/stabilityai/stable-video-diffusion-img2vid) and [extended frame](https://huggingface.co/stabilityai/stable-video-diffusion-img2vid-xt) checkpoints! + +
+ +## Tips + +Video generation is memory-intensive and one way to reduce your memory usage is to set `enable_forward_chunking` on the pipeline's UNet so you don't run the entire feedforward layer at once. Breaking it up into chunks in a loop is more efficient. + +Check out the [Text or image-to-video](text-img2vid) guide for more details about how certain parameters can affect video generation and how to optimize inference by reducing memory usage. + +## StableVideoDiffusionPipeline + +[[autodoc]] StableVideoDiffusionPipeline + +## StableVideoDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_video_diffusion.StableVideoDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/text2img.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/text2img.md new file mode 100644 index 0000000000000000000000000000000000000000..c7ac145712cb9eee11508a1134fdebae89dfb11d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/text2img.md @@ -0,0 +1,63 @@ + + +# Text-to-image + +
+ LoRA +
+ +The Stable Diffusion model was created by researchers and engineers from [CompVis](https://github.com/CompVis), [Stability AI](https://stability.ai/), [Runway](https://github.com/runwayml), and [LAION](https://laion.ai/). The [`StableDiffusionPipeline`] is capable of generating photorealistic images given any text input. It's trained on 512x512 images from a subset of the LAION-5B dataset. This model uses a frozen CLIP ViT-L/14 text encoder to condition the model on text prompts. With its 860M UNet and 123M text encoder, the model is relatively lightweight and can run on consumer GPUs. Latent diffusion is the research on top of which Stable Diffusion was built. It was proposed in [High-Resolution Image Synthesis with Latent Diffusion Models](https://huggingface.co/papers/2112.10752) by Robin Rombach, Andreas Blattmann, Dominik Lorenz, Patrick Esser, Björn Ommer. + +The abstract from the paper is: + +*By decomposing the image formation process into a sequential application of denoising autoencoders, diffusion models (DMs) achieve state-of-the-art synthesis results on image data and beyond. Additionally, their formulation allows for a guiding mechanism to control the image generation process without retraining. However, since these models typically operate directly in pixel space, optimization of powerful DMs often consumes hundreds of GPU days and inference is expensive due to sequential evaluations. To enable DM training on limited computational resources while retaining their quality and flexibility, we apply them in the latent space of powerful pretrained autoencoders. In contrast to previous work, training diffusion models on such a representation allows for the first time to reach a near-optimal point between complexity reduction and detail preservation, greatly boosting visual fidelity. By introducing cross-attention layers into the model architecture, we turn diffusion models into powerful and flexible generators for general conditioning inputs such as text or bounding boxes and high-resolution synthesis becomes possible in a convolutional manner. Our latent diffusion models (LDMs) achieve a new state of the art for image inpainting and highly competitive performance on various tasks, including unconditional image generation, semantic scene synthesis, and super-resolution, while significantly reducing computational requirements compared to pixel-based DMs. Code is available at https://github.com/CompVis/latent-diffusion.* + + + +Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently! + +If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations! + + + +## StableDiffusionPipeline + +[[autodoc]] StableDiffusionPipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_vae_slicing + - disable_vae_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + - enable_vae_tiling + - disable_vae_tiling + - load_textual_inversion + - from_single_file + - load_lora_weights + - save_lora_weights + +## StableDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput + +## FlaxStableDiffusionPipeline + +[[autodoc]] FlaxStableDiffusionPipeline + - all + - __call__ + +## FlaxStableDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_diffusion.FlaxStableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/upscale.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/upscale.md new file mode 100644 index 0000000000000000000000000000000000000000..53a95d501e34c074b6423120f4d569fcdef1bca0 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_diffusion/upscale.md @@ -0,0 +1,41 @@ + + +# Super-resolution + +
+ LoRA +
+ +The Stable Diffusion upscaler diffusion model was created by the researchers and engineers from [CompVis](https://github.com/CompVis), [Stability AI](https://stability.ai/), and [LAION](https://laion.ai/). It is used to enhance the resolution of input images by a factor of 4. + + + +Make sure to check out the Stable Diffusion [Tips](overview#tips) section to learn how to explore the tradeoff between scheduler speed and quality, and how to reuse pipeline components efficiently! + +If you're interested in using one of the official checkpoints for a task, explore the [CompVis](https://huggingface.co/CompVis), [Runway](https://huggingface.co/runwayml), and [Stability AI](https://huggingface.co/stabilityai) Hub organizations! + + + +## StableDiffusionUpscalePipeline + +[[autodoc]] StableDiffusionUpscalePipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + +## StableDiffusionPipelineOutput + +[[autodoc]] pipelines.stable_diffusion.StableDiffusionPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_unclip.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_unclip.md new file mode 100644 index 0000000000000000000000000000000000000000..9c281b28ab4d1deb722deb8b5ea4c97db77a71f0 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/stable_unclip.md @@ -0,0 +1,133 @@ + + +# Stable unCLIP + +
+ LoRA +
+ +Stable unCLIP checkpoints are finetuned from [Stable Diffusion 2.1](./stable_diffusion/stable_diffusion_2) checkpoints to condition on CLIP image embeddings. +Stable unCLIP still conditions on text embeddings. Given the two separate conditionings, stable unCLIP can be used +for text guided image variation. When combined with an unCLIP prior, it can also be used for full text to image generation. + +The abstract from the paper is: + +*Contrastive models like CLIP have been shown to learn robust representations of images that capture both semantics and style. To leverage these representations for image generation, we propose a two-stage model: a prior that generates a CLIP image embedding given a text caption, and a decoder that generates an image conditioned on the image embedding. We show that explicitly generating image representations improves image diversity with minimal loss in photorealism and caption similarity. Our decoders conditioned on image representations can also produce variations of an image that preserve both its semantics and style, while varying the non-essential details absent from the image representation. Moreover, the joint embedding space of CLIP enables language-guided image manipulations in a zero-shot fashion. We use diffusion models for the decoder and experiment with both autoregressive and diffusion models for the prior, finding that the latter are computationally more efficient and produce higher-quality samples.* + +## Tips + +Stable unCLIP takes `noise_level` as input during inference which determines how much noise is added to the image embeddings. A higher `noise_level` increases variation in the final un-noised images. By default, we do not add any additional noise to the image embeddings (`noise_level = 0`). + +### Text-to-Image Generation +Stable unCLIP can be leveraged for text-to-image generation by pipelining it with the prior model of KakaoBrain's open source DALL-E 2 replication [Karlo](https://huggingface.co/kakaobrain/karlo-v1-alpha): + +```python +import torch +from diffusers import UnCLIPScheduler, DDPMScheduler, StableUnCLIPPipeline +from diffusers.models import PriorTransformer +from transformers import CLIPTokenizer, CLIPTextModelWithProjection + +prior_model_id = "kakaobrain/karlo-v1-alpha" +data_type = torch.float16 +prior = PriorTransformer.from_pretrained(prior_model_id, subfolder="prior", torch_dtype=data_type) + +prior_text_model_id = "openai/clip-vit-large-patch14" +prior_tokenizer = CLIPTokenizer.from_pretrained(prior_text_model_id) +prior_text_model = CLIPTextModelWithProjection.from_pretrained(prior_text_model_id, torch_dtype=data_type) +prior_scheduler = UnCLIPScheduler.from_pretrained(prior_model_id, subfolder="prior_scheduler") +prior_scheduler = DDPMScheduler.from_config(prior_scheduler.config) + +stable_unclip_model_id = "stabilityai/stable-diffusion-2-1-unclip-small" + +pipe = StableUnCLIPPipeline.from_pretrained( + stable_unclip_model_id, + torch_dtype=data_type, + variant="fp16", + prior_tokenizer=prior_tokenizer, + prior_text_encoder=prior_text_model, + prior=prior, + prior_scheduler=prior_scheduler, +) + +pipe = pipe.to("cuda") +wave_prompt = "dramatic wave, the Oceans roar, Strong wave spiral across the oceans as the waves unfurl into roaring crests; perfect wave form; perfect wave shape; dramatic wave shape; wave shape unbelievable; wave; wave shape spectacular" + +image = pipe(prompt=wave_prompt).images[0] +image +``` + + +For text-to-image we use `stabilityai/stable-diffusion-2-1-unclip-small` as it was trained on CLIP ViT-L/14 embedding, the same as the Karlo model prior. [stabilityai/stable-diffusion-2-1-unclip](https://hf.co/stabilityai/stable-diffusion-2-1-unclip) was trained on OpenCLIP ViT-H, so we don't recommend its use. + + + +### Text guided Image-to-Image Variation + +```python +from diffusers import StableUnCLIPImg2ImgPipeline +from diffusers.utils import load_image +import torch + +pipe = StableUnCLIPImg2ImgPipeline.from_pretrained( + "stabilityai/stable-diffusion-2-1-unclip", torch_dtype=torch.float16, variation="fp16" +) +pipe = pipe.to("cuda") + +url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/stable_unclip/tarsila_do_amaral.png" +init_image = load_image(url) + +images = pipe(init_image).images +images[0].save("variation_image.png") +``` + +Optionally, you can also pass a prompt to `pipe` such as: + +```python +prompt = "A fantasy landscape, trending on artstation" + +image = pipe(init_image, prompt=prompt).images[0] +image +``` + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## StableUnCLIPPipeline + +[[autodoc]] StableUnCLIPPipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_vae_slicing + - disable_vae_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + +## StableUnCLIPImg2ImgPipeline + +[[autodoc]] StableUnCLIPImg2ImgPipeline + - all + - __call__ + - enable_attention_slicing + - disable_attention_slicing + - enable_vae_slicing + - disable_vae_slicing + - enable_xformers_memory_efficient_attention + - disable_xformers_memory_efficient_attention + +## ImagePipelineOutput +[[autodoc]] pipelines.ImagePipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/text_to_video.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/text_to_video.md new file mode 100644 index 0000000000000000000000000000000000000000..eca5b77b6da3fdab91e3ab85bf605dfda8f871ae --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/text_to_video.md @@ -0,0 +1,197 @@ + + + + +🧪 This pipeline is for research purposes only. + + + +# Text-to-video + +
+ LoRA +
+ +[ModelScope Text-to-Video Technical Report](https://huggingface.co/papers/2308.06571) is by Jiuniu Wang, Hangjie Yuan, Dayou Chen, Yingya Zhang, Xiang Wang, Shiwei Zhang. + +The abstract from the paper is: + +*This paper introduces ModelScopeT2V, a text-to-video synthesis model that evolves from a text-to-image synthesis model (i.e., Stable Diffusion). ModelScopeT2V incorporates spatio-temporal blocks to ensure consistent frame generation and smooth movement transitions. The model could adapt to varying frame numbers during training and inference, rendering it suitable for both image-text and video-text datasets. ModelScopeT2V brings together three components (i.e., VQGAN, a text encoder, and a denoising UNet), totally comprising 1.7 billion parameters, in which 0.5 billion parameters are dedicated to temporal capabilities. The model demonstrates superior performance over state-of-the-art methods across three evaluation metrics. The code and an online demo are available at https://modelscope.cn/models/damo/text-to-video-synthesis/summary.* + +You can find additional information about Text-to-Video on the [project page](https://modelscope.cn/models/damo/text-to-video-synthesis/summary), [original codebase](https://github.com/modelscope/modelscope/), and try it out in a [demo](https://huggingface.co/spaces/damo-vilab/modelscope-text-to-video-synthesis). Official checkpoints can be found at [damo-vilab](https://huggingface.co/damo-vilab) and [cerspense](https://huggingface.co/cerspense). + +## Usage example + +### `text-to-video-ms-1.7b` + +Let's start by generating a short video with the default length of 16 frames (2s at 8 fps): + +```python +import torch +from diffusers import DiffusionPipeline +from diffusers.utils import export_to_video + +pipe = DiffusionPipeline.from_pretrained("damo-vilab/text-to-video-ms-1.7b", torch_dtype=torch.float16, variant="fp16") +pipe = pipe.to("cuda") + +prompt = "Spiderman is surfing" +video_frames = pipe(prompt).frames[0] +video_path = export_to_video(video_frames) +video_path +``` + +Diffusers supports different optimization techniques to improve the latency +and memory footprint of a pipeline. Since videos are often more memory-heavy than images, +we can enable CPU offloading and VAE slicing to keep the memory footprint at bay. + +Let's generate a video of 8 seconds (64 frames) on the same GPU using CPU offloading and VAE slicing: + +```python +import torch +from diffusers import DiffusionPipeline +from diffusers.utils import export_to_video + +pipe = DiffusionPipeline.from_pretrained("damo-vilab/text-to-video-ms-1.7b", torch_dtype=torch.float16, variant="fp16") +pipe.enable_model_cpu_offload() + +# memory optimization +pipe.enable_vae_slicing() + +prompt = "Darth Vader surfing a wave" +video_frames = pipe(prompt, num_frames=64).frames[0] +video_path = export_to_video(video_frames) +video_path +``` + +It just takes **7 GBs of GPU memory** to generate the 64 video frames using PyTorch 2.0, "fp16" precision and the techniques mentioned above. + +We can also use a different scheduler easily, using the same method we'd use for Stable Diffusion: + +```python +import torch +from diffusers import DiffusionPipeline, DPMSolverMultistepScheduler +from diffusers.utils import export_to_video + +pipe = DiffusionPipeline.from_pretrained("damo-vilab/text-to-video-ms-1.7b", torch_dtype=torch.float16, variant="fp16") +pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config) +pipe.enable_model_cpu_offload() + +prompt = "Spiderman is surfing" +video_frames = pipe(prompt, num_inference_steps=25).frames[0] +video_path = export_to_video(video_frames) +video_path +``` + +Here are some sample outputs: + + + + + + +
+ An astronaut riding a horse. +
+ Darth vader surfing in waves. +
+ +### `cerspense/zeroscope_v2_576w` & `cerspense/zeroscope_v2_XL` + +Zeroscope are watermark-free model and have been trained on specific sizes such as `576x320` and `1024x576`. +One should first generate a video using the lower resolution checkpoint [`cerspense/zeroscope_v2_576w`](https://huggingface.co/cerspense/zeroscope_v2_576w) with [`TextToVideoSDPipeline`], +which can then be upscaled using [`VideoToVideoSDPipeline`] and [`cerspense/zeroscope_v2_XL`](https://huggingface.co/cerspense/zeroscope_v2_XL). + + +```py +import torch +from diffusers import DiffusionPipeline, DPMSolverMultistepScheduler +from diffusers.utils import export_to_video +from PIL import Image + +pipe = DiffusionPipeline.from_pretrained("cerspense/zeroscope_v2_576w", torch_dtype=torch.float16) +pipe.enable_model_cpu_offload() + +# memory optimization +pipe.unet.enable_forward_chunking(chunk_size=1, dim=1) +pipe.enable_vae_slicing() + +prompt = "Darth Vader surfing a wave" +video_frames = pipe(prompt, num_frames=24).frames[0] +video_path = export_to_video(video_frames) +video_path +``` + +Now the video can be upscaled: + +```py +pipe = DiffusionPipeline.from_pretrained("cerspense/zeroscope_v2_XL", torch_dtype=torch.float16) +pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config) +pipe.enable_model_cpu_offload() + +# memory optimization +pipe.unet.enable_forward_chunking(chunk_size=1, dim=1) +pipe.enable_vae_slicing() + +video = [Image.fromarray(frame).resize((1024, 576)) for frame in video_frames] + +video_frames = pipe(prompt, video=video, strength=0.6).frames[0] +video_path = export_to_video(video_frames) +video_path +``` + +Here are some sample outputs: + + + + + +
+ Darth vader surfing in waves. +
+ +## Tips + +Video generation is memory-intensive and one way to reduce your memory usage is to set `enable_forward_chunking` on the pipeline's UNet so you don't run the entire feedforward layer at once. Breaking it up into chunks in a loop is more efficient. + +Check out the [Text or image-to-video](text-img2vid) guide for more details about how certain parameters can affect video generation and how to optimize inference by reducing memory usage. + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## TextToVideoSDPipeline +[[autodoc]] TextToVideoSDPipeline + - all + - __call__ + +## VideoToVideoSDPipeline +[[autodoc]] VideoToVideoSDPipeline + - all + - __call__ + +## TextToVideoSDPipelineOutput +[[autodoc]] pipelines.text_to_video_synthesis.TextToVideoSDPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/text_to_video_zero.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/text_to_video_zero.md new file mode 100644 index 0000000000000000000000000000000000000000..a84ce0be110a2fc08c9272b9b6a7b670bd5ee3f6 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/text_to_video_zero.md @@ -0,0 +1,306 @@ + + +# Text2Video-Zero + +
+ LoRA +
+ +[Text2Video-Zero: Text-to-Image Diffusion Models are Zero-Shot Video Generators](https://huggingface.co/papers/2303.13439) is by Levon Khachatryan, Andranik Movsisyan, Vahram Tadevosyan, Roberto Henschel, [Zhangyang Wang](https://www.ece.utexas.edu/people/faculty/atlas-wang), Shant Navasardyan, [Humphrey Shi](https://www.humphreyshi.com). + +Text2Video-Zero enables zero-shot video generation using either: +1. A textual prompt +2. A prompt combined with guidance from poses or edges +3. Video Instruct-Pix2Pix (instruction-guided video editing) + +Results are temporally consistent and closely follow the guidance and textual prompts. + +![teaser-img](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/t2v_zero_teaser.png) + +The abstract from the paper is: + +*Recent text-to-video generation approaches rely on computationally heavy training and require large-scale video datasets. In this paper, we introduce a new task of zero-shot text-to-video generation and propose a low-cost approach (without any training or optimization) by leveraging the power of existing text-to-image synthesis methods (e.g., Stable Diffusion), making them suitable for the video domain. +Our key modifications include (i) enriching the latent codes of the generated frames with motion dynamics to keep the global scene and the background time consistent; and (ii) reprogramming frame-level self-attention using a new cross-frame attention of each frame on the first frame, to preserve the context, appearance, and identity of the foreground object. +Experiments show that this leads to low overhead, yet high-quality and remarkably consistent video generation. Moreover, our approach is not limited to text-to-video synthesis but is also applicable to other tasks such as conditional and content-specialized video generation, and Video Instruct-Pix2Pix, i.e., instruction-guided video editing. +As experiments show, our method performs comparably or sometimes better than recent approaches, despite not being trained on additional video data.* + +You can find additional information about Text2Video-Zero on the [project page](https://text2video-zero.github.io/), [paper](https://huggingface.co/papers/2303.13439), and [original codebase](https://github.com/Picsart-AI-Research/Text2Video-Zero). + +## Usage example + +### Text-To-Video + +To generate a video from prompt, run the following Python code: +```python +import torch +from diffusers import TextToVideoZeroPipeline +import imageio + +model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5" +pipe = TextToVideoZeroPipeline.from_pretrained(model_id, torch_dtype=torch.float16).to("cuda") + +prompt = "A panda is playing guitar on times square" +result = pipe(prompt=prompt).images +result = [(r * 255).astype("uint8") for r in result] +imageio.mimsave("video.mp4", result, fps=4) +``` +You can change these parameters in the pipeline call: +* Motion field strength (see the [paper](https://huggingface.co/papers/2303.13439), Sect. 3.3.1): + * `motion_field_strength_x` and `motion_field_strength_y`. Default: `motion_field_strength_x=12`, `motion_field_strength_y=12` +* `T` and `T'` (see the [paper](https://huggingface.co/papers/2303.13439), Sect. 3.3.1) + * `t0` and `t1` in the range `{0, ..., num_inference_steps}`. Default: `t0=45`, `t1=48` +* Video length: + * `video_length`, the number of frames video_length to be generated. Default: `video_length=8` + +We can also generate longer videos by doing the processing in a chunk-by-chunk manner: +```python +import torch +from diffusers import TextToVideoZeroPipeline +import numpy as np + +model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5" +pipe = TextToVideoZeroPipeline.from_pretrained(model_id, torch_dtype=torch.float16).to("cuda") +seed = 0 +video_length = 24 #24 ÷ 4fps = 6 seconds +chunk_size = 8 +prompt = "A panda is playing guitar on times square" + +# Generate the video chunk-by-chunk +result = [] +chunk_ids = np.arange(0, video_length, chunk_size - 1) +generator = torch.Generator(device="cuda") +for i in range(len(chunk_ids)): + print(f"Processing chunk {i + 1} / {len(chunk_ids)}") + ch_start = chunk_ids[i] + ch_end = video_length if i == len(chunk_ids) - 1 else chunk_ids[i + 1] + # Attach the first frame for Cross Frame Attention + frame_ids = [0] + list(range(ch_start, ch_end)) + # Fix the seed for the temporal consistency + generator.manual_seed(seed) + output = pipe(prompt=prompt, video_length=len(frame_ids), generator=generator, frame_ids=frame_ids) + result.append(output.images[1:]) + +# Concatenate chunks and save +result = np.concatenate(result) +result = [(r * 255).astype("uint8") for r in result] +imageio.mimsave("video.mp4", result, fps=4) +``` + + +- #### SDXL Support +In order to use the SDXL model when generating a video from prompt, use the `TextToVideoZeroSDXLPipeline` pipeline: + +```python +import torch +from diffusers import TextToVideoZeroSDXLPipeline + +model_id = "stabilityai/stable-diffusion-xl-base-1.0" +pipe = TextToVideoZeroSDXLPipeline.from_pretrained( + model_id, torch_dtype=torch.float16, variant="fp16", use_safetensors=True +).to("cuda") +``` + +### Text-To-Video with Pose Control +To generate a video from prompt with additional pose control + +1. Download a demo video + + ```python + from huggingface_hub import hf_hub_download + + filename = "__assets__/poses_skeleton_gifs/dance1_corr.mp4" + repo_id = "PAIR/Text2Video-Zero" + video_path = hf_hub_download(repo_type="space", repo_id=repo_id, filename=filename) + ``` + + +2. Read video containing extracted pose images + ```python + from PIL import Image + import imageio + + reader = imageio.get_reader(video_path, "ffmpeg") + frame_count = 8 + pose_images = [Image.fromarray(reader.get_data(i)) for i in range(frame_count)] + ``` + To extract pose from actual video, read [ControlNet documentation](controlnet). + +3. Run `StableDiffusionControlNetPipeline` with our custom attention processor + + ```python + import torch + from diffusers import StableDiffusionControlNetPipeline, ControlNetModel + from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor + + model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5" + controlnet = ControlNetModel.from_pretrained("lllyasviel/sd-controlnet-openpose", torch_dtype=torch.float16) + pipe = StableDiffusionControlNetPipeline.from_pretrained( + model_id, controlnet=controlnet, torch_dtype=torch.float16 + ).to("cuda") + + # Set the attention processor + pipe.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2)) + pipe.controlnet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2)) + + # fix latents for all frames + latents = torch.randn((1, 4, 64, 64), device="cuda", dtype=torch.float16).repeat(len(pose_images), 1, 1, 1) + + prompt = "Darth Vader dancing in a desert" + result = pipe(prompt=[prompt] * len(pose_images), image=pose_images, latents=latents).images + imageio.mimsave("video.mp4", result, fps=4) + ``` +- #### SDXL Support + + Since our attention processor also works with SDXL, it can be utilized to generate a video from prompt using ControlNet models powered by SDXL: + ```python + import torch + from diffusers import StableDiffusionXLControlNetPipeline, ControlNetModel + from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor + + controlnet_model_id = 'thibaud/controlnet-openpose-sdxl-1.0' + model_id = 'stabilityai/stable-diffusion-xl-base-1.0' + + controlnet = ControlNetModel.from_pretrained(controlnet_model_id, torch_dtype=torch.float16) + pipe = StableDiffusionControlNetPipeline.from_pretrained( + model_id, controlnet=controlnet, torch_dtype=torch.float16 + ).to('cuda') + + # Set the attention processor + pipe.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2)) + pipe.controlnet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2)) + + # fix latents for all frames + latents = torch.randn((1, 4, 128, 128), device="cuda", dtype=torch.float16).repeat(len(pose_images), 1, 1, 1) + + prompt = "Darth Vader dancing in a desert" + result = pipe(prompt=[prompt] * len(pose_images), image=pose_images, latents=latents).images + imageio.mimsave("video.mp4", result, fps=4) + ``` + +### Text-To-Video with Edge Control + +To generate a video from prompt with additional Canny edge control, follow the same steps described above for pose-guided generation using [Canny edge ControlNet model](https://huggingface.co/lllyasviel/sd-controlnet-canny). + + +### Video Instruct-Pix2Pix + +To perform text-guided video editing (with [InstructPix2Pix](pix2pix)): + +1. Download a demo video + + ```python + from huggingface_hub import hf_hub_download + + filename = "__assets__/pix2pix video/camel.mp4" + repo_id = "PAIR/Text2Video-Zero" + video_path = hf_hub_download(repo_type="space", repo_id=repo_id, filename=filename) + ``` + +2. Read video from path + ```python + from PIL import Image + import imageio + + reader = imageio.get_reader(video_path, "ffmpeg") + frame_count = 8 + video = [Image.fromarray(reader.get_data(i)) for i in range(frame_count)] + ``` + +3. Run `StableDiffusionInstructPix2PixPipeline` with our custom attention processor + ```python + import torch + from diffusers import StableDiffusionInstructPix2PixPipeline + from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor + + model_id = "timbrooks/instruct-pix2pix" + pipe = StableDiffusionInstructPix2PixPipeline.from_pretrained(model_id, torch_dtype=torch.float16).to("cuda") + pipe.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=3)) + + prompt = "make it Van Gogh Starry Night style" + result = pipe(prompt=[prompt] * len(video), image=video).images + imageio.mimsave("edited_video.mp4", result, fps=4) + ``` + + +### DreamBooth specialization + +Methods **Text-To-Video**, **Text-To-Video with Pose Control** and **Text-To-Video with Edge Control** +can run with custom [DreamBooth](../../training/dreambooth) models, as shown below for +[Canny edge ControlNet model](https://huggingface.co/lllyasviel/sd-controlnet-canny) and +[Avatar style DreamBooth](https://huggingface.co/PAIR/text2video-zero-controlnet-canny-avatar) model: + +1. Download a demo video + + ```python + from huggingface_hub import hf_hub_download + + filename = "__assets__/canny_videos_mp4/girl_turning.mp4" + repo_id = "PAIR/Text2Video-Zero" + video_path = hf_hub_download(repo_type="space", repo_id=repo_id, filename=filename) + ``` + +2. Read video from path + ```python + from PIL import Image + import imageio + + reader = imageio.get_reader(video_path, "ffmpeg") + frame_count = 8 + canny_edges = [Image.fromarray(reader.get_data(i)) for i in range(frame_count)] + ``` + +3. Run `StableDiffusionControlNetPipeline` with custom trained DreamBooth model + ```python + import torch + from diffusers import StableDiffusionControlNetPipeline, ControlNetModel + from diffusers.pipelines.text_to_video_synthesis.pipeline_text_to_video_zero import CrossFrameAttnProcessor + + # set model id to custom model + model_id = "PAIR/text2video-zero-controlnet-canny-avatar" + controlnet = ControlNetModel.from_pretrained("lllyasviel/sd-controlnet-canny", torch_dtype=torch.float16) + pipe = StableDiffusionControlNetPipeline.from_pretrained( + model_id, controlnet=controlnet, torch_dtype=torch.float16 + ).to("cuda") + + # Set the attention processor + pipe.unet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2)) + pipe.controlnet.set_attn_processor(CrossFrameAttnProcessor(batch_size=2)) + + # fix latents for all frames + latents = torch.randn((1, 4, 64, 64), device="cuda", dtype=torch.float16).repeat(len(canny_edges), 1, 1, 1) + + prompt = "oil painting of a beautiful girl avatar style" + result = pipe(prompt=[prompt] * len(canny_edges), image=canny_edges, latents=latents).images + imageio.mimsave("video.mp4", result, fps=4) + ``` + +You can filter out some available DreamBooth-trained models with [this link](https://huggingface.co/models?search=dreambooth). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## TextToVideoZeroPipeline +[[autodoc]] TextToVideoZeroPipeline + - all + - __call__ + +## TextToVideoZeroSDXLPipeline +[[autodoc]] TextToVideoZeroSDXLPipeline + - all + - __call__ + +## TextToVideoPipelineOutput +[[autodoc]] pipelines.text_to_video_synthesis.pipeline_text_to_video_zero.TextToVideoPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/unclip.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/unclip.md new file mode 100644 index 0000000000000000000000000000000000000000..943cebdb28a24111b36dd85bd3608cc534167116 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/unclip.md @@ -0,0 +1,37 @@ + + +# unCLIP + +[Hierarchical Text-Conditional Image Generation with CLIP Latents](https://huggingface.co/papers/2204.06125) is by Aditya Ramesh, Prafulla Dhariwal, Alex Nichol, Casey Chu, Mark Chen. The unCLIP model in 🤗 Diffusers comes from kakaobrain's [karlo](https://github.com/kakaobrain/karlo). + +The abstract from the paper is following: + +*Contrastive models like CLIP have been shown to learn robust representations of images that capture both semantics and style. To leverage these representations for image generation, we propose a two-stage model: a prior that generates a CLIP image embedding given a text caption, and a decoder that generates an image conditioned on the image embedding. We show that explicitly generating image representations improves image diversity with minimal loss in photorealism and caption similarity. Our decoders conditioned on image representations can also produce variations of an image that preserve both its semantics and style, while varying the non-essential details absent from the image representation. Moreover, the joint embedding space of CLIP enables language-guided image manipulations in a zero-shot fashion. We use diffusion models for the decoder and experiment with both autoregressive and diffusion models for the prior, finding that the latter are computationally more efficient and produce higher-quality samples.* + +You can find lucidrains' DALL-E 2 recreation at [lucidrains/DALLE2-pytorch](https://github.com/lucidrains/DALLE2-pytorch). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## UnCLIPPipeline +[[autodoc]] UnCLIPPipeline + - all + - __call__ + +## UnCLIPImageVariationPipeline +[[autodoc]] UnCLIPImageVariationPipeline + - all + - __call__ + +## ImagePipelineOutput +[[autodoc]] pipelines.ImagePipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/unidiffuser.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/unidiffuser.md new file mode 100644 index 0000000000000000000000000000000000000000..802aefea6be51bc9ee7e3c11b6910fd67f0879cf --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/unidiffuser.md @@ -0,0 +1,209 @@ + + +# UniDiffuser + +
+ LoRA +
+ +The UniDiffuser model was proposed in [One Transformer Fits All Distributions in Multi-Modal Diffusion at Scale](https://huggingface.co/papers/2303.06555) by Fan Bao, Shen Nie, Kaiwen Xue, Chongxuan Li, Shi Pu, Yaole Wang, Gang Yue, Yue Cao, Hang Su, Jun Zhu. + +The abstract from the paper is: + +*This paper proposes a unified diffusion framework (dubbed UniDiffuser) to fit all distributions relevant to a set of multi-modal data in one model. Our key insight is -- learning diffusion models for marginal, conditional, and joint distributions can be unified as predicting the noise in the perturbed data, where the perturbation levels (i.e. timesteps) can be different for different modalities. Inspired by the unified view, UniDiffuser learns all distributions simultaneously with a minimal modification to the original diffusion model -- perturbs data in all modalities instead of a single modality, inputs individual timesteps in different modalities, and predicts the noise of all modalities instead of a single modality. UniDiffuser is parameterized by a transformer for diffusion models to handle input types of different modalities. Implemented on large-scale paired image-text data, UniDiffuser is able to perform image, text, text-to-image, image-to-text, and image-text pair generation by setting proper timesteps without additional overhead. In particular, UniDiffuser is able to produce perceptually realistic samples in all tasks and its quantitative results (e.g., the FID and CLIP score) are not only superior to existing general-purpose models but also comparable to the bespoken models (e.g., Stable Diffusion and DALL-E 2) in representative tasks (e.g., text-to-image generation).* + +You can find the original codebase at [thu-ml/unidiffuser](https://github.com/thu-ml/unidiffuser) and additional checkpoints at [thu-ml](https://huggingface.co/thu-ml). + + + +There is currently an issue on PyTorch 1.X where the output images are all black or the pixel values become `NaNs`. This issue can be mitigated by switching to PyTorch 2.X. + + + +This pipeline was contributed by [dg845](https://github.com/dg845). ❤️ + +## Usage Examples + +Because the UniDiffuser model is trained to model the joint distribution of (image, text) pairs, it is capable of performing a diverse range of generation tasks: + +### Unconditional Image and Text Generation + +Unconditional generation (where we start from only latents sampled from a standard Gaussian prior) from a [`UniDiffuserPipeline`] will produce a (image, text) pair: + +```python +import torch + +from diffusers import UniDiffuserPipeline + +device = "cuda" +model_id_or_path = "thu-ml/unidiffuser-v1" +pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16) +pipe.to(device) + +# Unconditional image and text generation. The generation task is automatically inferred. +sample = pipe(num_inference_steps=20, guidance_scale=8.0) +image = sample.images[0] +text = sample.text[0] +image.save("unidiffuser_joint_sample_image.png") +print(text) +``` + +This is also called "joint" generation in the UniDiffuser paper, since we are sampling from the joint image-text distribution. + +Note that the generation task is inferred from the inputs used when calling the pipeline. +It is also possible to manually specify the unconditional generation task ("mode") manually with [`UniDiffuserPipeline.set_joint_mode`]: + +```python +# Equivalent to the above. +pipe.set_joint_mode() +sample = pipe(num_inference_steps=20, guidance_scale=8.0) +``` + +When the mode is set manually, subsequent calls to the pipeline will use the set mode without attempting to infer the mode. +You can reset the mode with [`UniDiffuserPipeline.reset_mode`], after which the pipeline will once again infer the mode. + +You can also generate only an image or only text (which the UniDiffuser paper calls "marginal" generation since we sample from the marginal distribution of images and text, respectively): + +```python +# Unlike other generation tasks, image-only and text-only generation don't use classifier-free guidance +# Image-only generation +pipe.set_image_mode() +sample_image = pipe(num_inference_steps=20).images[0] +# Text-only generation +pipe.set_text_mode() +sample_text = pipe(num_inference_steps=20).text[0] +``` + +### Text-to-Image Generation + +UniDiffuser is also capable of sampling from conditional distributions; that is, the distribution of images conditioned on a text prompt or the distribution of texts conditioned on an image. +Here is an example of sampling from the conditional image distribution (text-to-image generation or text-conditioned image generation): + +```python +import torch + +from diffusers import UniDiffuserPipeline + +device = "cuda" +model_id_or_path = "thu-ml/unidiffuser-v1" +pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16) +pipe.to(device) + +# Text-to-image generation +prompt = "an elephant under the sea" + +sample = pipe(prompt=prompt, num_inference_steps=20, guidance_scale=8.0) +t2i_image = sample.images[0] +t2i_image +``` + +The `text2img` mode requires that either an input `prompt` or `prompt_embeds` be supplied. You can set the `text2img` mode manually with [`UniDiffuserPipeline.set_text_to_image_mode`]. + +### Image-to-Text Generation + +Similarly, UniDiffuser can also produce text samples given an image (image-to-text or image-conditioned text generation): + +```python +import torch + +from diffusers import UniDiffuserPipeline +from diffusers.utils import load_image + +device = "cuda" +model_id_or_path = "thu-ml/unidiffuser-v1" +pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16) +pipe.to(device) + +# Image-to-text generation +image_url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/unidiffuser/unidiffuser_example_image.jpg" +init_image = load_image(image_url).resize((512, 512)) + +sample = pipe(image=init_image, num_inference_steps=20, guidance_scale=8.0) +i2t_text = sample.text[0] +print(i2t_text) +``` + +The `img2text` mode requires that an input `image` be supplied. You can set the `img2text` mode manually with [`UniDiffuserPipeline.set_image_to_text_mode`]. + +### Image Variation + +The UniDiffuser authors suggest performing image variation through a "round-trip" generation method, where given an input image, we first perform an image-to-text generation, and then perform a text-to-image generation on the outputs of the first generation. +This produces a new image which is semantically similar to the input image: + +```python +import torch + +from diffusers import UniDiffuserPipeline +from diffusers.utils import load_image + +device = "cuda" +model_id_or_path = "thu-ml/unidiffuser-v1" +pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16) +pipe.to(device) + +# Image variation can be performed with an image-to-text generation followed by a text-to-image generation: +# 1. Image-to-text generation +image_url = "https://huggingface.co/datasets/hf-internal-testing/diffusers-images/resolve/main/unidiffuser/unidiffuser_example_image.jpg" +init_image = load_image(image_url).resize((512, 512)) + +sample = pipe(image=init_image, num_inference_steps=20, guidance_scale=8.0) +i2t_text = sample.text[0] +print(i2t_text) + +# 2. Text-to-image generation +sample = pipe(prompt=i2t_text, num_inference_steps=20, guidance_scale=8.0) +final_image = sample.images[0] +final_image.save("unidiffuser_image_variation_sample.png") +``` + +### Text Variation + +Similarly, text variation can be performed on an input prompt with a text-to-image generation followed by a image-to-text generation: + +```python +import torch + +from diffusers import UniDiffuserPipeline + +device = "cuda" +model_id_or_path = "thu-ml/unidiffuser-v1" +pipe = UniDiffuserPipeline.from_pretrained(model_id_or_path, torch_dtype=torch.float16) +pipe.to(device) + +# Text variation can be performed with a text-to-image generation followed by a image-to-text generation: +# 1. Text-to-image generation +prompt = "an elephant under the sea" + +sample = pipe(prompt=prompt, num_inference_steps=20, guidance_scale=8.0) +t2i_image = sample.images[0] +t2i_image.save("unidiffuser_text2img_sample_image.png") + +# 2. Image-to-text generation +sample = pipe(image=t2i_image, num_inference_steps=20, guidance_scale=8.0) +final_prompt = sample.text[0] +print(final_prompt) +``` + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## UniDiffuserPipeline +[[autodoc]] UniDiffuserPipeline + - all + - __call__ + +## ImageTextPipelineOutput +[[autodoc]] pipelines.ImageTextPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/value_guided_sampling.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/value_guided_sampling.md new file mode 100644 index 0000000000000000000000000000000000000000..5aaee9090cef0486f0eee43e8b93ec3e84b690e2 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/value_guided_sampling.md @@ -0,0 +1,38 @@ + + +# Value-guided planning + + + +🧪 This is an experimental pipeline for reinforcement learning! + + + +This pipeline is based on the [Planning with Diffusion for Flexible Behavior Synthesis](https://huggingface.co/papers/2205.09991) paper by Michael Janner, Yilun Du, Joshua B. Tenenbaum, Sergey Levine. + +The abstract from the paper is: + +*Model-based reinforcement learning methods often use learning only for the purpose of estimating an approximate dynamics model, offloading the rest of the decision-making work to classical trajectory optimizers. While conceptually simple, this combination has a number of empirical shortcomings, suggesting that learned models may not be well-suited to standard trajectory optimization. In this paper, we consider what it would look like to fold as much of the trajectory optimization pipeline as possible into the modeling problem, such that sampling from the model and planning with it become nearly identical. The core of our technical approach lies in a diffusion probabilistic model that plans by iteratively denoising trajectories. We show how classifier-guided sampling and image inpainting can be reinterpreted as coherent planning strategies, explore the unusual and useful properties of diffusion-based planning methods, and demonstrate the effectiveness of our framework in control settings that emphasize long-horizon decision-making and test-time flexibility.* + +You can find additional information about the model on the [project page](https://diffusion-planning.github.io/), the [original codebase](https://github.com/jannerm/diffuser), or try it out in a demo [notebook](https://colab.research.google.com/drive/1rXm8CX4ZdN5qivjJ2lhwhkOmt_m0CvU0#scrollTo=6HXJvhyqcITc&uniqifier=1). + +The script to run the model is available [here](https://github.com/huggingface/diffusers/tree/main/examples/reinforcement_learning). + + + +Make sure to check out the Schedulers [guide](../../using-diffusers/schedulers) to learn how to explore the tradeoff between scheduler speed and quality, and see the [reuse components across pipelines](../../using-diffusers/loading#reuse-a-pipeline) section to learn how to efficiently load the same components into multiple pipelines. + + + +## ValueGuidedRLPipeline +[[autodoc]] diffusers.experimental.ValueGuidedRLPipeline diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/visualcloze.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/visualcloze.md new file mode 100644 index 0000000000000000000000000000000000000000..1a4f96a50d638099adacef370a0c0467f15e7074 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/visualcloze.md @@ -0,0 +1,300 @@ + + +# VisualCloze + +[VisualCloze: A Universal Image Generation Framework via Visual In-Context Learning](https://huggingface.co/papers/2504.07960) is an innovative in-context learning based universal image generation framework that offers key capabilities: +1. Support for various in-domain tasks +2. Generalization to unseen tasks through in-context learning +3. Unify multiple tasks into one step and generate both target image and intermediate results +4. Support reverse-engineering conditions from target images + +## Overview + +The abstract from the paper is: + +*Recent progress in diffusion models significantly advances various image generation tasks. However, the current mainstream approach remains focused on building task-specific models, which have limited efficiency when supporting a wide range of different needs. While universal models attempt to address this limitation, they face critical challenges, including generalizable task instruction, appropriate task distributions, and unified architectural design. To tackle these challenges, we propose VisualCloze, a universal image generation framework, which supports a wide range of in-domain tasks, generalization to unseen ones, unseen unification of multiple tasks, and reverse generation. Unlike existing methods that rely on language-based task instruction, leading to task ambiguity and weak generalization, we integrate visual in-context learning, allowing models to identify tasks from visual demonstrations. Meanwhile, the inherent sparsity of visual task distributions hampers the learning of transferable knowledge across tasks. To this end, we introduce Graph200K, a graph-structured dataset that establishes various interrelated tasks, enhancing task density and transferable knowledge. Furthermore, we uncover that our unified image generation formulation shared a consistent objective with image infilling, enabling us to leverage the strong generative priors of pre-trained infilling models without modifying the architectures. The codes, dataset, and models are available at https://visualcloze.github.io.* + +## Inference + +### Model loading + +VisualCloze is a two-stage cascade pipeline, containing `VisualClozeGenerationPipeline` and `VisualClozeUpsamplingPipeline`. +- In `VisualClozeGenerationPipeline`, each image is downsampled before concatenating images into a grid layout, avoiding excessively high resolutions. VisualCloze releases two models suitable for diffusers, i.e., [VisualClozePipeline-384](https://huggingface.co/VisualCloze/VisualClozePipeline-384) and [VisualClozePipeline-512](https://huggingface.co/VisualCloze/VisualClozePipeline-384), which downsample images to resolutions of 384 and 512, respectively. +- `VisualClozeUpsamplingPipeline` uses [SDEdit](https://huggingface.co/papers/2108.01073) to enable high-resolution image synthesis. + +The `VisualClozePipeline` integrates both stages to support convenient end-to-end sampling, while also allowing users to utilize each pipeline independently as needed. + +### Input Specifications + +#### Task and Content Prompts +- Task prompt: Required to describe the generation task intention +- Content prompt: Optional description or caption of the target image +- When content prompt is not needed, pass `None` +- For batch inference, pass `List[str|None]` + +#### Image Input Format +- Format: `List[List[Image|None]]` +- Structure: + - All rows except the last represent in-context examples + - Last row represents the current query (target image set to `None`) +- For batch inference, pass `List[List[List[Image|None]]]` + +#### Resolution Control +- Default behavior: + - Initial generation in the first stage: area of ${pipe.resolution}^2$ + - Upsampling in the second stage: 3x factor +- Custom resolution: Adjust using `upsampling_height` and `upsampling_width` parameters + +### Examples + +For comprehensive examples covering a wide range of tasks, please refer to the [Online Demo](https://huggingface.co/spaces/VisualCloze/VisualCloze) and [GitHub Repository](https://github.com/lzyhha/VisualCloze). Below are simple examples for three cases: mask-to-image conversion, edge detection, and subject-driven generation. + +#### Example for mask2image + +```python +import torch +from diffusers import VisualClozePipeline +from diffusers.utils import load_image + +pipe = VisualClozePipeline.from_pretrained("VisualCloze/VisualClozePipeline-384", resolution=384, torch_dtype=torch.bfloat16) +pipe.to("cuda") + +# Load in-context images (make sure the paths are correct and accessible) +image_paths = [ + # in-context examples + [ + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_incontext-example-1_mask.jpg'), + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_incontext-example-1_image.jpg'), + ], + # query with the target image + [ + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_query_mask.jpg'), + None, # No image needed for the target image + ], +] + +# Task and content prompt +task_prompt = "In each row, a logical task is demonstrated to achieve [IMAGE2] an aesthetically pleasing photograph based on [IMAGE1] sam 2-generated masks with rich color coding." +content_prompt = """Majestic photo of a golden eagle perched on a rocky outcrop in a mountainous landscape. +The eagle is positioned in the right foreground, facing left, with its sharp beak and keen eyes prominently visible. +Its plumage is a mix of dark brown and golden hues, with intricate feather details. +The background features a soft-focus view of snow-capped mountains under a cloudy sky, creating a serene and grandiose atmosphere. +The foreground includes rugged rocks and patches of green moss. Photorealistic, medium depth of field, +soft natural lighting, cool color palette, high contrast, sharp focus on the eagle, blurred background, +tranquil, majestic, wildlife photography.""" + +# Run the pipeline +image_result = pipe( + task_prompt=task_prompt, + content_prompt=content_prompt, + image=image_paths, + upsampling_width=1344, + upsampling_height=768, + upsampling_strength=0.4, + guidance_scale=30, + num_inference_steps=30, + max_sequence_length=512, + generator=torch.Generator("cpu").manual_seed(0) +).images[0][0] + +# Save the resulting image +image_result.save("visualcloze.png") +``` + +#### Example for edge-detection + +```python +import torch +from diffusers import VisualClozePipeline +from diffusers.utils import load_image + +pipe = VisualClozePipeline.from_pretrained("VisualCloze/VisualClozePipeline-384", resolution=384, torch_dtype=torch.bfloat16) +pipe.to("cuda") + +# Load in-context images (make sure the paths are correct and accessible) +image_paths = [ + # in-context examples + [ + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_incontext-example-1_image.jpg'), + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_incontext-example-1_edge.jpg'), + ], + [ + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_incontext-example-2_image.jpg'), + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_incontext-example-2_edge.jpg'), + ], + # query with the target image + [ + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_edgedetection_query_image.jpg'), + None, # No image needed for the target image + ], +] + +# Task and content prompt +task_prompt = "Each row illustrates a pathway from [IMAGE1] a sharp and beautifully composed photograph to [IMAGE2] edge map with natural well-connected outlines using a clear logical task." +content_prompt = "" + +# Run the pipeline +image_result = pipe( + task_prompt=task_prompt, + content_prompt=content_prompt, + image=image_paths, + upsampling_width=864, + upsampling_height=1152, + upsampling_strength=0.4, + guidance_scale=30, + num_inference_steps=30, + max_sequence_length=512, + generator=torch.Generator("cpu").manual_seed(0) +).images[0][0] + +# Save the resulting image +image_result.save("visualcloze.png") +``` + +#### Example for subject-driven generation + +```python +import torch +from diffusers import VisualClozePipeline +from diffusers.utils import load_image + +pipe = VisualClozePipeline.from_pretrained("VisualCloze/VisualClozePipeline-384", resolution=384, torch_dtype=torch.bfloat16) +pipe.to("cuda") + +# Load in-context images (make sure the paths are correct and accessible) +image_paths = [ + # in-context examples + [ + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-1_reference.jpg'), + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-1_depth.jpg'), + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-1_image.jpg'), + ], + [ + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-2_reference.jpg'), + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-2_depth.jpg'), + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_incontext-example-2_image.jpg'), + ], + # query with the target image + [ + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_query_reference.jpg'), + load_image('https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_subjectdriven_query_depth.jpg'), + None, # No image needed for the target image + ], +] + +# Task and content prompt +task_prompt = """Each row describes a process that begins with [IMAGE1] an image containing the key object, +[IMAGE2] depth map revealing gray-toned spatial layers and results in +[IMAGE3] an image with artistic qualitya high-quality image with exceptional detail.""" +content_prompt = """A vintage porcelain collector's item. Beneath a blossoming cherry tree in early spring, +this treasure is photographed up close, with soft pink petals drifting through the air and vibrant blossoms framing the scene.""" + +# Run the pipeline +image_result = pipe( + task_prompt=task_prompt, + content_prompt=content_prompt, + image=image_paths, + upsampling_width=1024, + upsampling_height=1024, + upsampling_strength=0.2, + guidance_scale=30, + num_inference_steps=30, + max_sequence_length=512, + generator=torch.Generator("cpu").manual_seed(0) +).images[0][0] + +# Save the resulting image +image_result.save("visualcloze.png") +``` + +#### Utilize each pipeline independently + +```python +import torch +from diffusers import VisualClozeGenerationPipeline, FluxFillPipeline as VisualClozeUpsamplingPipeline +from diffusers.utils import load_image +from PIL import Image + +pipe = VisualClozeGenerationPipeline.from_pretrained( + "VisualCloze/VisualClozePipeline-384", resolution=384, torch_dtype=torch.bfloat16 +) +pipe.to("cuda") + +image_paths = [ + # in-context examples + [ + load_image( + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_incontext-example-1_mask.jpg" + ), + load_image( + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_incontext-example-1_image.jpg" + ), + ], + # query with the target image + [ + load_image( + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/visualcloze/visualcloze_mask2image_query_mask.jpg" + ), + None, # No image needed for the target image + ], +] +task_prompt = "In each row, a logical task is demonstrated to achieve [IMAGE2] an aesthetically pleasing photograph based on [IMAGE1] sam 2-generated masks with rich color coding." +content_prompt = "Majestic photo of a golden eagle perched on a rocky outcrop in a mountainous landscape. The eagle is positioned in the right foreground, facing left, with its sharp beak and keen eyes prominently visible. Its plumage is a mix of dark brown and golden hues, with intricate feather details. The background features a soft-focus view of snow-capped mountains under a cloudy sky, creating a serene and grandiose atmosphere. The foreground includes rugged rocks and patches of green moss. Photorealistic, medium depth of field, soft natural lighting, cool color palette, high contrast, sharp focus on the eagle, blurred background, tranquil, majestic, wildlife photography." + +# Stage 1: Generate initial image +image = pipe( + task_prompt=task_prompt, + content_prompt=content_prompt, + image=image_paths, + guidance_scale=30, + num_inference_steps=30, + max_sequence_length=512, + generator=torch.Generator("cpu").manual_seed(0), +).images[0][0] + +# Stage 2 (optional): Upsample the generated image +pipe_upsample = VisualClozeUpsamplingPipeline.from_pipe(pipe) +pipe_upsample.to("cuda") + +mask_image = Image.new("RGB", image.size, (255, 255, 255)) + +image = pipe_upsample( + image=image, + mask_image=mask_image, + prompt=content_prompt, + width=1344, + height=768, + strength=0.4, + guidance_scale=30, + num_inference_steps=30, + max_sequence_length=512, + generator=torch.Generator("cpu").manual_seed(0), +).images[0] + +image.save("visualcloze.png") +``` + +## VisualClozePipeline + +[[autodoc]] VisualClozePipeline + - all + - __call__ + +## VisualClozeGenerationPipeline + +[[autodoc]] VisualClozeGenerationPipeline + - all + - __call__ diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/wan.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/wan.md new file mode 100644 index 0000000000000000000000000000000000000000..09503125f5c5541b0a36c122607f57bb97133510 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/wan.md @@ -0,0 +1,519 @@ + + +# Wan + +
+ LoRA +
+ +[Wan 2.1](https://github.com/Wan-Video/Wan2.1) by the Alibaba Wan Team. + + + +## Generating Videos with Wan 2.1 + +We will first need to install some additional dependencies. + +```shell +pip install -u ftfy imageio-ffmpeg imageio +``` + +### Text to Video Generation + +The following example requires 11GB VRAM to run and uses the smaller `Wan-AI/Wan2.1-T2V-1.3B-Diffusers` model. You can switch it out +for the larger `Wan2.1-I2V-14B-720P-Diffusers` or `Wan-AI/Wan2.1-I2V-14B-480P-Diffusers` if you have at least 35GB VRAM available. + +```python +from diffusers import WanPipeline +from diffusers.utils import export_to_video + +# Available models: Wan-AI/Wan2.1-I2V-14B-720P-Diffusers or Wan-AI/Wan2.1-I2V-14B-480P-Diffusers +model_id = "Wan-AI/Wan2.1-T2V-1.3B-Diffusers" + +pipe = WanPipeline.from_pretrained(model_id, torch_dtype=torch.bfloat16) +pipe.enable_model_cpu_offload() + +prompt = "A cat and a dog baking a cake together in a kitchen. The cat is carefully measuring flour, while the dog is stirring the batter with a wooden spoon. The kitchen is cozy, with sunlight streaming through the window." +negative_prompt = "Bright tones, overexposed, static, blurred details, subtitles, style, works, paintings, images, static, overall gray, worst quality, low quality, JPEG compression residue, ugly, incomplete, extra fingers, poorly drawn hands, poorly drawn faces, deformed, disfigured, misshapen limbs, fused fingers, still picture, messy background, three legs, many people in the background, walking backwards" +num_frames = 33 + +frames = pipe(prompt=prompt, negative_prompt=negative_prompt, num_frames=num_frames).frames[0] +export_to_video(frames, "wan-t2v.mp4", fps=16) +``` + + +You can improve the quality of the generated video by running the decoding step in full precision. + + +```python +from diffusers import WanPipeline, AutoencoderKLWan +from diffusers.utils import export_to_video + +model_id = "Wan-AI/Wan2.1-T2V-1.3B-Diffusers" + +vae = AutoencoderKLWan.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32) +pipe = WanPipeline.from_pretrained(model_id, vae=vae, torch_dtype=torch.bfloat16) + +# replace this with pipe.to("cuda") if you have sufficient VRAM +pipe.enable_model_cpu_offload() + +prompt = "A cat and a dog baking a cake together in a kitchen. The cat is carefully measuring flour, while the dog is stirring the batter with a wooden spoon. The kitchen is cozy, with sunlight streaming through the window." +negative_prompt = "Bright tones, overexposed, static, blurred details, subtitles, style, works, paintings, images, static, overall gray, worst quality, low quality, JPEG compression residue, ugly, incomplete, extra fingers, poorly drawn hands, poorly drawn faces, deformed, disfigured, misshapen limbs, fused fingers, still picture, messy background, three legs, many people in the background, walking backwards" +num_frames = 33 + +frames = pipe(prompt=prompt, num_frames=num_frames).frames[0] +export_to_video(frames, "wan-t2v.mp4", fps=16) +``` + +### Image to Video Generation + +The Image to Video pipeline requires loading the `AutoencoderKLWan` and the `CLIPVisionModel` components in full precision. The following example will need at least +35GB of VRAM to run. + +```python +import torch +import numpy as np +from diffusers import AutoencoderKLWan, WanImageToVideoPipeline +from diffusers.utils import export_to_video, load_image +from transformers import CLIPVisionModel + +# Available models: Wan-AI/Wan2.1-I2V-14B-480P-Diffusers, Wan-AI/Wan2.1-I2V-14B-720P-Diffusers +model_id = "Wan-AI/Wan2.1-I2V-14B-480P-Diffusers" +image_encoder = CLIPVisionModel.from_pretrained( + model_id, subfolder="image_encoder", torch_dtype=torch.float32 +) +vae = AutoencoderKLWan.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32) +pipe = WanImageToVideoPipeline.from_pretrained( + model_id, vae=vae, image_encoder=image_encoder, torch_dtype=torch.bfloat16 +) + +# replace this with pipe.to("cuda") if you have sufficient VRAM +pipe.enable_model_cpu_offload() + +image = load_image( + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/astronaut.jpg" +) + +max_area = 480 * 832 +aspect_ratio = image.height / image.width +mod_value = pipe.vae_scale_factor_spatial * pipe.transformer.config.patch_size[1] +height = round(np.sqrt(max_area * aspect_ratio)) // mod_value * mod_value +width = round(np.sqrt(max_area / aspect_ratio)) // mod_value * mod_value +image = image.resize((width, height)) + +prompt = ( + "An astronaut hatching from an egg, on the surface of the moon, the darkness and depth of space realised in " + "the background. High quality, ultrarealistic detail and breath-taking movie-like camera shot." +) +negative_prompt = "Bright tones, overexposed, static, blurred details, subtitles, style, works, paintings, images, static, overall gray, worst quality, low quality, JPEG compression residue, ugly, incomplete, extra fingers, poorly drawn hands, poorly drawn faces, deformed, disfigured, misshapen limbs, fused fingers, still picture, messy background, three legs, many people in the background, walking backwards" + +num_frames = 33 + +output = pipe( + image=image, + prompt=prompt, + negative_prompt=negative_prompt, + height=height, + width=width, + num_frames=num_frames, + guidance_scale=5.0, +).frames[0] +export_to_video(output, "wan-i2v.mp4", fps=16) +``` + +### First and Last Frame Interpolation + +```python +import numpy as np +import torch +import torchvision.transforms.functional as TF +from diffusers import AutoencoderKLWan, WanImageToVideoPipeline +from diffusers.utils import export_to_video, load_image +from transformers import CLIPVisionModel + + +model_id = "Wan-AI/Wan2.1-FLF2V-14B-720P-diffusers" +image_encoder = CLIPVisionModel.from_pretrained(model_id, subfolder="image_encoder", torch_dtype=torch.float32) +vae = AutoencoderKLWan.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32) +pipe = WanImageToVideoPipeline.from_pretrained( + model_id, vae=vae, image_encoder=image_encoder, torch_dtype=torch.bfloat16 +) +pipe.to("cuda") + +first_frame = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/flf2v_input_first_frame.png") +last_frame = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/flf2v_input_last_frame.png") + +def aspect_ratio_resize(image, pipe, max_area=720 * 1280): + aspect_ratio = image.height / image.width + mod_value = pipe.vae_scale_factor_spatial * pipe.transformer.config.patch_size[1] + height = round(np.sqrt(max_area * aspect_ratio)) // mod_value * mod_value + width = round(np.sqrt(max_area / aspect_ratio)) // mod_value * mod_value + image = image.resize((width, height)) + return image, height, width + +def center_crop_resize(image, height, width): + # Calculate resize ratio to match first frame dimensions + resize_ratio = max(width / image.width, height / image.height) + + # Resize the image + width = round(image.width * resize_ratio) + height = round(image.height * resize_ratio) + size = [width, height] + image = TF.center_crop(image, size) + + return image, height, width + +first_frame, height, width = aspect_ratio_resize(first_frame, pipe) +if last_frame.size != first_frame.size: + last_frame, _, _ = center_crop_resize(last_frame, height, width) + +prompt = "CG animation style, a small blue bird takes off from the ground, flapping its wings. The bird's feathers are delicate, with a unique pattern on its chest. The background shows a blue sky with white clouds under bright sunshine. The camera follows the bird upward, capturing its flight and the vastness of the sky from a close-up, low-angle perspective." + +output = pipe( + image=first_frame, last_image=last_frame, prompt=prompt, height=height, width=width, guidance_scale=5.5 +).frames[0] +export_to_video(output, "output.mp4", fps=16) +``` + +### Video to Video Generation + +```python +import torch +from diffusers.utils import load_video, export_to_video +from diffusers import AutoencoderKLWan, WanVideoToVideoPipeline, UniPCMultistepScheduler + +# Available models: Wan-AI/Wan2.1-T2V-14B-Diffusers, Wan-AI/Wan2.1-T2V-1.3B-Diffusers +model_id = "Wan-AI/Wan2.1-T2V-1.3B-Diffusers" +vae = AutoencoderKLWan.from_pretrained( + model_id, subfolder="vae", torch_dtype=torch.float32 +) +pipe = WanVideoToVideoPipeline.from_pretrained( + model_id, vae=vae, torch_dtype=torch.bfloat16 +) +flow_shift = 3.0 # 5.0 for 720P, 3.0 for 480P +pipe.scheduler = UniPCMultistepScheduler.from_config( + pipe.scheduler.config, flow_shift=flow_shift +) +# change to pipe.to("cuda") if you have sufficient VRAM +pipe.enable_model_cpu_offload() + +prompt = "A robot standing on a mountain top. The sun is setting in the background" +negative_prompt = "Bright tones, overexposed, static, blurred details, subtitles, style, works, paintings, images, static, overall gray, worst quality, low quality, JPEG compression residue, ugly, incomplete, extra fingers, poorly drawn hands, poorly drawn faces, deformed, disfigured, misshapen limbs, fused fingers, still picture, messy background, three legs, many people in the background, walking backwards" +video = load_video( + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/hiker.mp4" +) +output = pipe( + video=video, + prompt=prompt, + negative_prompt=negative_prompt, + height=480, + width=512, + guidance_scale=7.0, + strength=0.7, +).frames[0] + +export_to_video(output, "wan-v2v.mp4", fps=16) +``` + +## Memory Optimizations for Wan 2.1 + +Base inference with the large 14B Wan 2.1 models can take up to 35GB of VRAM when generating videos at 720p resolution. We'll outline a few memory optimizations we can apply to reduce the VRAM required to run the model. + +We'll use `Wan-AI/Wan2.1-I2V-14B-720P-Diffusers` model in these examples to demonstrate the memory savings, but the techniques are applicable to all model checkpoints. + +### Group Offloading the Transformer and UMT5 Text Encoder + +Find more information about group offloading [here](../optimization/memory.md) + +#### Block Level Group Offloading + +We can reduce our VRAM requirements by applying group offloading to the larger model components of the pipeline; the `WanTransformer3DModel` and `UMT5EncoderModel`. Group offloading will break up the individual modules of a model and offload/onload them onto your GPU as needed during inference. In this example, we'll apply `block_level` offloading, which will group the modules in a model into blocks of size `num_blocks_per_group` and offload/onload them to GPU. Moving to between CPU and GPU does add latency to the inference process. You can trade off between latency and memory savings by increasing or decreasing the `num_blocks_per_group`. + +The following example will now only require 14GB of VRAM to run, but will take approximately 30 minutes to generate a video. + +```python +import torch +import numpy as np +from diffusers import AutoencoderKLWan, WanTransformer3DModel, WanImageToVideoPipeline +from diffusers.hooks.group_offloading import apply_group_offloading +from diffusers.utils import export_to_video, load_image +from transformers import UMT5EncoderModel, CLIPVisionModel + +# Available models: Wan-AI/Wan2.1-I2V-14B-480P-Diffusers, Wan-AI/Wan2.1-I2V-14B-720P-Diffusers +model_id = "Wan-AI/Wan2.1-I2V-14B-720P-Diffusers" +image_encoder = CLIPVisionModel.from_pretrained( + model_id, subfolder="image_encoder", torch_dtype=torch.float32 +) + +text_encoder = UMT5EncoderModel.from_pretrained(model_id, subfolder="text_encoder", torch_dtype=torch.bfloat16) +vae = AutoencoderKLWan.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32) +transformer = WanTransformer3DModel.from_pretrained(model_id, subfolder="transformer", torch_dtype=torch.bfloat16) + +onload_device = torch.device("cuda") +offload_device = torch.device("cpu") + +apply_group_offloading(text_encoder, + onload_device=onload_device, + offload_device=offload_device, + offload_type="block_level", + num_blocks_per_group=4 +) + +transformer.enable_group_offload( + onload_device=onload_device, + offload_device=offload_device, + offload_type="block_level", + num_blocks_per_group=4, +) +pipe = WanImageToVideoPipeline.from_pretrained( + model_id, + vae=vae, + transformer=transformer, + text_encoder=text_encoder, + image_encoder=image_encoder, + torch_dtype=torch.bfloat16 +) +# Since we've offloaded the larger models already, we can move the rest of the model components to GPU +pipe.to("cuda") + +image = load_image( + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/astronaut.jpg" +) + +max_area = 720 * 832 +aspect_ratio = image.height / image.width +mod_value = pipe.vae_scale_factor_spatial * pipe.transformer.config.patch_size[1] +height = round(np.sqrt(max_area * aspect_ratio)) // mod_value * mod_value +width = round(np.sqrt(max_area / aspect_ratio)) // mod_value * mod_value +image = image.resize((width, height)) + +prompt = ( + "An astronaut hatching from an egg, on the surface of the moon, the darkness and depth of space realised in " + "the background. High quality, ultrarealistic detail and breath-taking movie-like camera shot." +) +negative_prompt = "Bright tones, overexposed, static, blurred details, subtitles, style, works, paintings, images, static, overall gray, worst quality, low quality, JPEG compression residue, ugly, incomplete, extra fingers, poorly drawn hands, poorly drawn faces, deformed, disfigured, misshapen limbs, fused fingers, still picture, messy background, three legs, many people in the background, walking backwards" + +num_frames = 33 + +output = pipe( + image=image, + prompt=prompt, + negative_prompt=negative_prompt, + height=height, + width=width, + num_frames=num_frames, + guidance_scale=5.0, +).frames[0] + +export_to_video(output, "wan-i2v.mp4", fps=16) +``` + +#### Block Level Group Offloading with CUDA Streams + +We can speed up group offloading inference, by enabling the use of [CUDA streams](https://pytorch.org/docs/stable/generated/torch.cuda.Stream.html). However, using CUDA streams requires moving the model parameters into pinned memory. This allocation is handled by Pytorch under the hood, and can result in a significant spike in CPU RAM usage. Please consider this option if your CPU RAM is atleast 2X the size of the model you are group offloading. + +In the following example we will use CUDA streams when group offloading the `WanTransformer3DModel`. When testing on an A100, this example will require 14GB of VRAM, 52GB of CPU RAM, but will generate a video in approximately 9 minutes. + +```python +import torch +import numpy as np +from diffusers import AutoencoderKLWan, WanTransformer3DModel, WanImageToVideoPipeline +from diffusers.hooks.group_offloading import apply_group_offloading +from diffusers.utils import export_to_video, load_image +from transformers import UMT5EncoderModel, CLIPVisionModel + +# Available models: Wan-AI/Wan2.1-I2V-14B-480P-Diffusers, Wan-AI/Wan2.1-I2V-14B-720P-Diffusers +model_id = "Wan-AI/Wan2.1-I2V-14B-720P-Diffusers" +image_encoder = CLIPVisionModel.from_pretrained( + model_id, subfolder="image_encoder", torch_dtype=torch.float32 +) + +text_encoder = UMT5EncoderModel.from_pretrained(model_id, subfolder="text_encoder", torch_dtype=torch.bfloat16) +vae = AutoencoderKLWan.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32) +transformer = WanTransformer3DModel.from_pretrained(model_id, subfolder="transformer", torch_dtype=torch.bfloat16) + +onload_device = torch.device("cuda") +offload_device = torch.device("cpu") + +apply_group_offloading(text_encoder, + onload_device=onload_device, + offload_device=offload_device, + offload_type="block_level", + num_blocks_per_group=4 +) + +transformer.enable_group_offload( + onload_device=onload_device, + offload_device=offload_device, + offload_type="leaf_level", + use_stream=True +) +pipe = WanImageToVideoPipeline.from_pretrained( + model_id, + vae=vae, + transformer=transformer, + text_encoder=text_encoder, + image_encoder=image_encoder, + torch_dtype=torch.bfloat16 +) +# Since we've offloaded the larger models already, we can move the rest of the model components to GPU +pipe.to("cuda") + +image = load_image( + "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/astronaut.jpg" +) + +max_area = 720 * 832 +aspect_ratio = image.height / image.width +mod_value = pipe.vae_scale_factor_spatial * pipe.transformer.config.patch_size[1] +height = round(np.sqrt(max_area * aspect_ratio)) // mod_value * mod_value +width = round(np.sqrt(max_area / aspect_ratio)) // mod_value * mod_value +image = image.resize((width, height)) + +prompt = ( + "An astronaut hatching from an egg, on the surface of the moon, the darkness and depth of space realised in " + "the background. High quality, ultrarealistic detail and breath-taking movie-like camera shot." +) +negative_prompt = "Bright tones, overexposed, static, blurred details, subtitles, style, works, paintings, images, static, overall gray, worst quality, low quality, JPEG compression residue, ugly, incomplete, extra fingers, poorly drawn hands, poorly drawn faces, deformed, disfigured, misshapen limbs, fused fingers, still picture, messy background, three legs, many people in the background, walking backwards" + +num_frames = 33 + +output = pipe( + image=image, + prompt=prompt, + negative_prompt=negative_prompt, + height=height, + width=width, + num_frames=num_frames, + guidance_scale=5.0, +).frames[0] + +export_to_video(output, "wan-i2v.mp4", fps=16) +``` + +### Applying Layerwise Casting to the Transformer + +Find more information about layerwise casting [here](../optimization/memory.md) + +In this example, we will model offloading with layerwise casting. Layerwise casting will downcast each layer's weights to `torch.float8_e4m3fn`, temporarily upcast to `torch.bfloat16` during the forward pass of the layer, then revert to `torch.float8_e4m3fn` afterward. This approach reduces memory requirements by approximately 50% while introducing a minor quality reduction in the generated video due to the precision trade-off. + +This example will require 20GB of VRAM. + +```python +import torch +import numpy as np +from diffusers import AutoencoderKLWan, WanTransformer3DModel, WanImageToVideoPipeline +from diffusers.hooks.group_offloading import apply_group_offloading +from diffusers.utils import export_to_video, load_image +from transformers import UMT5EncoderModel, CLIPVisionModel + +model_id = "Wan-AI/Wan2.1-I2V-14B-720P-Diffusers" +image_encoder = CLIPVisionModel.from_pretrained( + model_id, subfolder="image_encoder", torch_dtype=torch.float32 +) +text_encoder = UMT5EncoderModel.from_pretrained(model_id, subfolder="text_encoder", torch_dtype=torch.bfloat16) +vae = AutoencoderKLWan.from_pretrained(model_id, subfolder="vae", torch_dtype=torch.float32) + +transformer = WanTransformer3DModel.from_pretrained(model_id, subfolder="transformer", torch_dtype=torch.bfloat16) +transformer.enable_layerwise_casting(storage_dtype=torch.float8_e4m3fn, compute_dtype=torch.bfloat16) + +pipe = WanImageToVideoPipeline.from_pretrained( + model_id, + vae=vae, + transformer=transformer, + text_encoder=text_encoder, + image_encoder=image_encoder, + torch_dtype=torch.bfloat16 +) +pipe.enable_model_cpu_offload() +image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/astronaut.jpg") + +max_area = 720 * 832 +aspect_ratio = image.height / image.width +mod_value = pipe.vae_scale_factor_spatial * pipe.transformer.config.patch_size[1] +height = round(np.sqrt(max_area * aspect_ratio)) // mod_value * mod_value +width = round(np.sqrt(max_area / aspect_ratio)) // mod_value * mod_value +image = image.resize((width, height)) +prompt = ( + "An astronaut hatching from an egg, on the surface of the moon, the darkness and depth of space realised in " + "the background. High quality, ultrarealistic detail and breath-taking movie-like camera shot." +) +negative_prompt = "Bright tones, overexposed, static, blurred details, subtitles, style, works, paintings, images, static, overall gray, worst quality, low quality, JPEG compression residue, ugly, incomplete, extra fingers, poorly drawn hands, poorly drawn faces, deformed, disfigured, misshapen limbs, fused fingers, still picture, messy background, three legs, many people in the background, walking backwards" +num_frames = 33 + +output = pipe( + image=image, + prompt=prompt, + negative_prompt=negative_prompt, + height=height, + width=width, + num_frames=num_frames, + num_inference_steps=50, + guidance_scale=5.0, +).frames[0] +export_to_video(output, "wan-i2v.mp4", fps=16) +``` + +## Using a Custom Scheduler + +Wan can be used with many different schedulers, each with their own benefits regarding speed and generation quality. By default, Wan uses the `UniPCMultistepScheduler(prediction_type="flow_prediction", use_flow_sigmas=True, flow_shift=3.0)` scheduler. You can use a different scheduler as follows: + +```python +from diffusers import FlowMatchEulerDiscreteScheduler, UniPCMultistepScheduler, WanPipeline + +scheduler_a = FlowMatchEulerDiscreteScheduler(shift=5.0) +scheduler_b = UniPCMultistepScheduler(prediction_type="flow_prediction", use_flow_sigmas=True, flow_shift=4.0) + +pipe = WanPipeline.from_pretrained("Wan-AI/Wan2.1-T2V-1.3B-Diffusers", scheduler=) + +# or, +pipe.scheduler = +``` + +## Using Single File Loading with Wan 2.1 + +The `WanTransformer3DModel` and `AutoencoderKLWan` models support loading checkpoints in their original format via the `from_single_file` loading +method. + +```python +import torch +from diffusers import WanPipeline, WanTransformer3DModel + +ckpt_path = "https://huggingface.co/Comfy-Org/Wan_2.1_ComfyUI_repackaged/blob/main/split_files/diffusion_models/wan2.1_t2v_1.3B_bf16.safetensors" +transformer = WanTransformer3DModel.from_single_file(ckpt_path, torch_dtype=torch.bfloat16) + +pipe = WanPipeline.from_pretrained("Wan-AI/Wan2.1-T2V-1.3B-Diffusers", transformer=transformer) +``` + +## Recommendations for Inference +- Keep `AutencoderKLWan` in `torch.float32` for better decoding quality. +- `num_frames` should satisfy the following constraint: `(num_frames - 1) % 4 == 0` +- For smaller resolution videos, try lower values of `shift` (between `2.0` to `5.0`) in the [Scheduler](https://huggingface.co/docs/diffusers/main/en/api/schedulers/flow_match_euler_discrete#diffusers.FlowMatchEulerDiscreteScheduler.shift). For larger resolution videos, try higher values (between `7.0` and `12.0`). The default value is `3.0` for Wan. + +## WanPipeline + +[[autodoc]] WanPipeline + - all + - __call__ + +## WanImageToVideoPipeline + +[[autodoc]] WanImageToVideoPipeline + - all + - __call__ + +## WanPipelineOutput + +[[autodoc]] pipelines.wan.pipeline_output.WanPipelineOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/wuerstchen.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/wuerstchen.md new file mode 100644 index 0000000000000000000000000000000000000000..da6ef2cffc28837204d9a6091abdd9bae64c34d7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/pipelines/wuerstchen.md @@ -0,0 +1,167 @@ + + +# Würstchen + +
+ LoRA +
+ + + +[Wuerstchen: An Efficient Architecture for Large-Scale Text-to-Image Diffusion Models](https://huggingface.co/papers/2306.00637) is by Pablo Pernias, Dominic Rampas, Mats L. Richter and Christopher Pal and Marc Aubreville. + +The abstract from the paper is: + +*We introduce Würstchen, a novel architecture for text-to-image synthesis that combines competitive performance with unprecedented cost-effectiveness for large-scale text-to-image diffusion models. A key contribution of our work is to develop a latent diffusion technique in which we learn a detailed but extremely compact semantic image representation used to guide the diffusion process. This highly compressed representation of an image provides much more detailed guidance compared to latent representations of language and this significantly reduces the computational requirements to achieve state-of-the-art results. Our approach also improves the quality of text-conditioned image generation based on our user preference study. The training requirements of our approach consists of 24,602 A100-GPU hours - compared to Stable Diffusion 2.1's 200,000 GPU hours. Our approach also requires less training data to achieve these results. Furthermore, our compact latent representations allows us to perform inference over twice as fast, slashing the usual costs and carbon footprint of a state-of-the-art (SOTA) diffusion model significantly, without compromising the end performance. In a broader comparison against SOTA models our approach is substantially more efficient and compares favorably in terms of image quality. We believe that this work motivates more emphasis on the prioritization of both performance and computational accessibility.* + +## Würstchen Overview +Würstchen is a diffusion model, whose text-conditional model works in a highly compressed latent space of images. Why is this important? Compressing data can reduce computational costs for both training and inference by magnitudes. Training on 1024x1024 images is way more expensive than training on 32x32. Usually, other works make use of a relatively small compression, in the range of 4x - 8x spatial compression. Würstchen takes this to an extreme. Through its novel design, we achieve a 42x spatial compression. This was unseen before because common methods fail to faithfully reconstruct detailed images after 16x spatial compression. Würstchen employs a two-stage compression, what we call Stage A and Stage B. Stage A is a VQGAN, and Stage B is a Diffusion Autoencoder (more details can be found in the [paper](https://huggingface.co/papers/2306.00637)). A third model, Stage C, is learned in that highly compressed latent space. This training requires fractions of the compute used for current top-performing models, while also allowing cheaper and faster inference. + +## Würstchen v2 comes to Diffusers + +After the initial paper release, we have improved numerous things in the architecture, training and sampling, making Würstchen competitive to current state-of-the-art models in many ways. We are excited to release this new version together with Diffusers. Here is a list of the improvements. + +- Higher resolution (1024x1024 up to 2048x2048) +- Faster inference +- Multi Aspect Resolution Sampling +- Better quality + + +We are releasing 3 checkpoints for the text-conditional image generation model (Stage C). Those are: + +- v2-base +- v2-aesthetic +- **(default)** v2-interpolated (50% interpolation between v2-base and v2-aesthetic) + +We recommend using v2-interpolated, as it has a nice touch of both photorealism and aesthetics. Use v2-base for finetunings as it does not have a style bias and use v2-aesthetic for very artistic generations. +A comparison can be seen here: + + + +## Text-to-Image Generation + +For the sake of usability, Würstchen can be used with a single pipeline. This pipeline can be used as follows: + +```python +import torch +from diffusers import AutoPipelineForText2Image +from diffusers.pipelines.wuerstchen import DEFAULT_STAGE_C_TIMESTEPS + +pipe = AutoPipelineForText2Image.from_pretrained("warp-ai/wuerstchen", torch_dtype=torch.float16).to("cuda") + +caption = "Anthropomorphic cat dressed as a fire fighter" +images = pipe( + caption, + width=1024, + height=1536, + prior_timesteps=DEFAULT_STAGE_C_TIMESTEPS, + prior_guidance_scale=4.0, + num_images_per_prompt=2, +).images +``` + +For explanation purposes, we can also initialize the two main pipelines of Würstchen individually. Würstchen consists of 3 stages: Stage C, Stage B, Stage A. They all have different jobs and work only together. When generating text-conditional images, Stage C will first generate the latents in a very compressed latent space. This is what happens in the `prior_pipeline`. Afterwards, the generated latents will be passed to Stage B, which decompresses the latents into a bigger latent space of a VQGAN. These latents can then be decoded by Stage A, which is a VQGAN, into the pixel-space. Stage B & Stage A are both encapsulated in the `decoder_pipeline`. For more details, take a look at the [paper](https://huggingface.co/papers/2306.00637). + +```python +import torch +from diffusers import WuerstchenDecoderPipeline, WuerstchenPriorPipeline +from diffusers.pipelines.wuerstchen import DEFAULT_STAGE_C_TIMESTEPS + +device = "cuda" +dtype = torch.float16 +num_images_per_prompt = 2 + +prior_pipeline = WuerstchenPriorPipeline.from_pretrained( + "warp-ai/wuerstchen-prior", torch_dtype=dtype +).to(device) +decoder_pipeline = WuerstchenDecoderPipeline.from_pretrained( + "warp-ai/wuerstchen", torch_dtype=dtype +).to(device) + +caption = "Anthropomorphic cat dressed as a fire fighter" +negative_prompt = "" + +prior_output = prior_pipeline( + prompt=caption, + height=1024, + width=1536, + timesteps=DEFAULT_STAGE_C_TIMESTEPS, + negative_prompt=negative_prompt, + guidance_scale=4.0, + num_images_per_prompt=num_images_per_prompt, +) +decoder_output = decoder_pipeline( + image_embeddings=prior_output.image_embeddings, + prompt=caption, + negative_prompt=negative_prompt, + guidance_scale=0.0, + output_type="pil", +).images[0] +decoder_output +``` + +## Speed-Up Inference +You can make use of `torch.compile` function and gain a speed-up of about 2-3x: + +```python +prior_pipeline.prior = torch.compile(prior_pipeline.prior, mode="reduce-overhead", fullgraph=True) +decoder_pipeline.decoder = torch.compile(decoder_pipeline.decoder, mode="reduce-overhead", fullgraph=True) +``` + +## Limitations + +- Due to the high compression employed by Würstchen, generations can lack a good amount +of detail. To our human eye, this is especially noticeable in faces, hands etc. +- **Images can only be generated in 128-pixel steps**, e.g. the next higher resolution +after 1024x1024 is 1152x1152 +- The model lacks the ability to render correct text in images +- The model often does not achieve photorealism +- Difficult compositional prompts are hard for the model + +The original codebase, as well as experimental ideas, can be found at [dome272/Wuerstchen](https://github.com/dome272/Wuerstchen). + + +## WuerstchenCombinedPipeline + +[[autodoc]] WuerstchenCombinedPipeline + - all + - __call__ + +## WuerstchenPriorPipeline + +[[autodoc]] WuerstchenPriorPipeline + - all + - __call__ + +## WuerstchenPriorPipelineOutput + +[[autodoc]] pipelines.wuerstchen.pipeline_wuerstchen_prior.WuerstchenPriorPipelineOutput + +## WuerstchenDecoderPipeline + +[[autodoc]] WuerstchenDecoderPipeline + - all + - __call__ + +## Citation + +```bibtex + @misc{pernias2023wuerstchen, + title={Wuerstchen: An Efficient Architecture for Large-Scale Text-to-Image Diffusion Models}, + author={Pablo Pernias and Dominic Rampas and Mats L. Richter and Christopher J. Pal and Marc Aubreville}, + year={2023}, + eprint={2306.00637}, + archivePrefix={arXiv}, + primaryClass={cs.CV} + } +``` diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/quantization.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/quantization.md new file mode 100644 index 0000000000000000000000000000000000000000..e2ca990190e63cc51c991ff941097c1d40b637bd --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/quantization.md @@ -0,0 +1,46 @@ + + +# Quantization + +Quantization techniques reduce memory and computational costs by representing weights and activations with lower-precision data types like 8-bit integers (int8). This enables loading larger models you normally wouldn't be able to fit into memory, and speeding up inference. + + + +Learn how to quantize models in the [Quantization](../quantization/overview) guide. + + + +## PipelineQuantizationConfig + +[[autodoc]] quantizers.PipelineQuantizationConfig + +## BitsAndBytesConfig + +[[autodoc]] BitsAndBytesConfig + +## GGUFQuantizationConfig + +[[autodoc]] GGUFQuantizationConfig + +## QuantoConfig + +[[autodoc]] QuantoConfig + +## TorchAoConfig + +[[autodoc]] TorchAoConfig + +## DiffusersQuantizer + +[[autodoc]] quantizers.base.DiffusersQuantizer diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/cm_stochastic_iterative.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/cm_stochastic_iterative.md new file mode 100644 index 0000000000000000000000000000000000000000..89e50b5d6b614f8fb8bd4408f78c2566caeaad6d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/cm_stochastic_iterative.md @@ -0,0 +1,27 @@ + + +# CMStochasticIterativeScheduler + +[Consistency Models](https://huggingface.co/papers/2303.01469) by Yang Song, Prafulla Dhariwal, Mark Chen, and Ilya Sutskever introduced a multistep and onestep scheduler (Algorithm 1) that is capable of generating good samples in one or a small number of steps. + +The abstract from the paper is: + +*Diffusion models have significantly advanced the fields of image, audio, and video generation, but they depend on an iterative sampling process that causes slow generation. To overcome this limitation, we propose consistency models, a new family of models that generate high quality samples by directly mapping noise to data. They support fast one-step generation by design, while still allowing multistep sampling to trade compute for sample quality. They also support zero-shot data editing, such as image inpainting, colorization, and super-resolution, without requiring explicit training on these tasks. Consistency models can be trained either by distilling pre-trained diffusion models, or as standalone generative models altogether. Through extensive experiments, we demonstrate that they outperform existing distillation techniques for diffusion models in one- and few-step sampling, achieving the new state-of-the-art FID of 3.55 on CIFAR-10 and 6.20 on ImageNet 64x64 for one-step generation. When trained in isolation, consistency models become a new family of generative models that can outperform existing one-step, non-adversarial generative models on standard benchmarks such as CIFAR-10, ImageNet 64x64 and LSUN 256x256.* + +The original codebase can be found at [openai/consistency_models](https://github.com/openai/consistency_models). + +## CMStochasticIterativeScheduler +[[autodoc]] CMStochasticIterativeScheduler + +## CMStochasticIterativeSchedulerOutput +[[autodoc]] schedulers.scheduling_consistency_models.CMStochasticIterativeSchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/consistency_decoder.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/consistency_decoder.md new file mode 100644 index 0000000000000000000000000000000000000000..a9eaa5336dcda592d1d947e838027d040b6f39f7 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/consistency_decoder.md @@ -0,0 +1,21 @@ + + +# ConsistencyDecoderScheduler + +This scheduler is a part of the [`ConsistencyDecoderPipeline`] and was introduced in [DALL-E 3](https://openai.com/dall-e-3). + +The original codebase can be found at [openai/consistency_models](https://github.com/openai/consistency_models). + + +## ConsistencyDecoderScheduler +[[autodoc]] schedulers.scheduling_consistency_decoder.ConsistencyDecoderScheduler diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/cosine_dpm.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/cosine_dpm.md new file mode 100644 index 0000000000000000000000000000000000000000..03703b8449e55027c7793d298e5ebce2e0c912d5 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/cosine_dpm.md @@ -0,0 +1,24 @@ + + +# CosineDPMSolverMultistepScheduler + +The [`CosineDPMSolverMultistepScheduler`] is a variant of [`DPMSolverMultistepScheduler`] with cosine schedule, proposed by Nichol and Dhariwal (2021). +It is being used in the [Stable Audio Open](https://huggingface.co/papers/2407.14358) paper and the [Stability-AI/stable-audio-tool](https://github.com/Stability-AI/stable-audio-tools) codebase. + +This scheduler was contributed by [Yoach Lacombe](https://huggingface.co/ylacombe). + +## CosineDPMSolverMultistepScheduler +[[autodoc]] CosineDPMSolverMultistepScheduler + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ddim.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ddim.md new file mode 100644 index 0000000000000000000000000000000000000000..952855dbd2ac50e5b5e66350c993f0ed620323c4 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ddim.md @@ -0,0 +1,82 @@ + + +# DDIMScheduler + +[Denoising Diffusion Implicit Models](https://huggingface.co/papers/2010.02502) (DDIM) by Jiaming Song, Chenlin Meng and Stefano Ermon. + +The abstract from the paper is: + +*Denoising diffusion probabilistic models (DDPMs) have achieved high quality image generation without adversarial training, yet they require simulating a Markov chain for many steps to produce a sample. +To accelerate sampling, we present denoising diffusion implicit models (DDIMs), a more efficient class of iterative implicit probabilistic models +with the same training procedure as DDPMs. In DDPMs, the generative process is defined as the reverse of a Markovian diffusion process. +We construct a class of non-Markovian diffusion processes that lead to the same training objective, but whose reverse process can be much faster to sample from. +We empirically demonstrate that DDIMs can produce high quality samples 10× to 50× faster in terms of wall-clock time compared to DDPMs, allow us to trade off computation for sample quality, and can perform semantically meaningful image interpolation directly in the latent space.* + +The original codebase of this paper can be found at [ermongroup/ddim](https://github.com/ermongroup/ddim), and you can contact the author on [tsong.me](https://tsong.me/). + +## Tips + +The paper [Common Diffusion Noise Schedules and Sample Steps are Flawed](https://huggingface.co/papers/2305.08891) claims that a mismatch between the training and inference settings leads to suboptimal inference generation results for Stable Diffusion. To fix this, the authors propose: + + + +🧪 This is an experimental feature! + + + +1. rescale the noise schedule to enforce zero terminal signal-to-noise ratio (SNR) + +```py +pipe.scheduler = DDIMScheduler.from_config(pipe.scheduler.config, rescale_betas_zero_snr=True) +``` + +2. train a model with `v_prediction` (add the following argument to the [train_text_to_image.py](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image.py) or [train_text_to_image_lora.py](https://github.com/huggingface/diffusers/blob/main/examples/text_to_image/train_text_to_image_lora.py) scripts) + +```bash +--prediction_type="v_prediction" +``` + +3. change the sampler to always start from the last timestep + +```py +pipe.scheduler = DDIMScheduler.from_config(pipe.scheduler.config, timestep_spacing="trailing") +``` + +4. rescale classifier-free guidance to prevent over-exposure + +```py +image = pipe(prompt, guidance_rescale=0.7).images[0] +``` + +For example: + +```py +from diffusers import DiffusionPipeline, DDIMScheduler +import torch + +pipe = DiffusionPipeline.from_pretrained("ptx0/pseudo-journey-v2", torch_dtype=torch.float16) +pipe.scheduler = DDIMScheduler.from_config( + pipe.scheduler.config, rescale_betas_zero_snr=True, timestep_spacing="trailing" +) +pipe.to("cuda") + +prompt = "A lion in galaxies, spirals, nebulae, stars, smoke, iridescent, intricate detail, octane render, 8k" +image = pipe(prompt, guidance_rescale=0.7).images[0] +image +``` + +## DDIMScheduler +[[autodoc]] DDIMScheduler + +## DDIMSchedulerOutput +[[autodoc]] schedulers.scheduling_ddim.DDIMSchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ddim_cogvideox.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ddim_cogvideox.md new file mode 100644 index 0000000000000000000000000000000000000000..d3ff380306c7bb233b0af7262b3cd640fee16141 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ddim_cogvideox.md @@ -0,0 +1,19 @@ + + +# CogVideoXDDIMScheduler + +`CogVideoXDDIMScheduler` is based on [Denoising Diffusion Implicit Models](https://huggingface.co/papers/2010.02502), specifically for CogVideoX models. + +## CogVideoXDDIMScheduler + +[[autodoc]] CogVideoXDDIMScheduler diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ddim_inverse.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ddim_inverse.md new file mode 100644 index 0000000000000000000000000000000000000000..82069cce4c538b5eac76547a1cc34b2af661978f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ddim_inverse.md @@ -0,0 +1,19 @@ + + +# DDIMInverseScheduler + +`DDIMInverseScheduler` is the inverted scheduler from [Denoising Diffusion Implicit Models](https://huggingface.co/papers/2010.02502) (DDIM) by Jiaming Song, Chenlin Meng and Stefano Ermon. +The implementation is mostly based on the DDIM inversion definition from [Null-text Inversion for Editing Real Images using Guided Diffusion Models](https://huggingface.co/papers/2211.09794). + +## DDIMInverseScheduler +[[autodoc]] DDIMInverseScheduler diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ddpm.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ddpm.md new file mode 100644 index 0000000000000000000000000000000000000000..cfe3815b67323546c770b97df5e5296fab91db9a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ddpm.md @@ -0,0 +1,25 @@ + + +# DDPMScheduler + +[Denoising Diffusion Probabilistic Models](https://huggingface.co/papers/2006.11239) (DDPM) by Jonathan Ho, Ajay Jain and Pieter Abbeel proposes a diffusion based model of the same name. In the context of the 🤗 Diffusers library, DDPM refers to the discrete denoising scheduler from the paper as well as the pipeline. + +The abstract from the paper is: + +*We present high quality image synthesis results using diffusion probabilistic models, a class of latent variable models inspired by considerations from nonequilibrium thermodynamics. Our best results are obtained by training on a weighted variational bound designed according to a novel connection between diffusion probabilistic models and denoising score matching with Langevin dynamics, and our models naturally admit a progressive lossy decompression scheme that can be interpreted as a generalization of autoregressive decoding. On the unconditional CIFAR10 dataset, we obtain an Inception score of 9.46 and a state-of-the-art FID score of 3.17. On 256x256 LSUN, we obtain sample quality similar to ProgressiveGAN. Our implementation is available at [this https URL](https://github.com/hojonathanho/diffusion).* + +## DDPMScheduler +[[autodoc]] DDPMScheduler + +## DDPMSchedulerOutput +[[autodoc]] schedulers.scheduling_ddpm.DDPMSchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/deis.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/deis.md new file mode 100644 index 0000000000000000000000000000000000000000..4a449b32bf0d1fe9b42e6a4dd7270924a04af47a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/deis.md @@ -0,0 +1,34 @@ + + +# DEISMultistepScheduler + +Diffusion Exponential Integrator Sampler (DEIS) is proposed in [Fast Sampling of Diffusion Models with Exponential Integrator](https://huggingface.co/papers/2204.13902) by Qinsheng Zhang and Yongxin Chen. `DEISMultistepScheduler` is a fast high order solver for diffusion ordinary differential equations (ODEs). + +This implementation modifies the polynomial fitting formula in log-rho space instead of the original linear `t` space in the DEIS paper. The modification enjoys closed-form coefficients for exponential multistep update instead of replying on the numerical solver. + +The abstract from the paper is: + +*The past few years have witnessed the great success of Diffusion models~(DMs) in generating high-fidelity samples in generative modeling tasks. A major limitation of the DM is its notoriously slow sampling procedure which normally requires hundreds to thousands of time discretization steps of the learned diffusion process to reach the desired accuracy. Our goal is to develop a fast sampling method for DMs with a much less number of steps while retaining high sample quality. To this end, we systematically analyze the sampling procedure in DMs and identify key factors that affect the sample quality, among which the method of discretization is most crucial. By carefully examining the learned diffusion process, we propose Diffusion Exponential Integrator Sampler~(DEIS). It is based on the Exponential Integrator designed for discretizing ordinary differential equations (ODEs) and leverages a semilinear structure of the learned diffusion process to reduce the discretization error. The proposed method can be applied to any DMs and can generate high-fidelity samples in as few as 10 steps. In our experiments, it takes about 3 minutes on one A6000 GPU to generate 50k images from CIFAR10. Moreover, by directly using pre-trained DMs, we achieve the state-of-art sampling performance when the number of score function evaluation~(NFE) is limited, e.g., 4.17 FID with 10 NFEs, 3.37 FID, and 9.74 IS with only 15 NFEs on CIFAR10. Code is available at [this https URL](https://github.com/qsh-zh/deis).* + +## Tips + +It is recommended to set `solver_order` to 2 or 3, while `solver_order=1` is equivalent to [`DDIMScheduler`]. + +Dynamic thresholding from [Imagen](https://huggingface.co/papers/2205.11487) is supported, and for pixel-space +diffusion models, you can set `thresholding=True` to use the dynamic thresholding. + +## DEISMultistepScheduler +[[autodoc]] DEISMultistepScheduler + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/dpm_discrete.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/dpm_discrete.md new file mode 100644 index 0000000000000000000000000000000000000000..cb95f3781ecf2f9cd2fe410d7ccc58bf895cd138 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/dpm_discrete.md @@ -0,0 +1,23 @@ + + +# KDPM2DiscreteScheduler + +The `KDPM2DiscreteScheduler` is inspired by the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper, and the scheduler is ported from and created by [Katherine Crowson](https://github.com/crowsonkb/). + +The original codebase can be found at [crowsonkb/k-diffusion](https://github.com/crowsonkb/k-diffusion). + +## KDPM2DiscreteScheduler +[[autodoc]] KDPM2DiscreteScheduler + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/dpm_discrete_ancestral.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/dpm_discrete_ancestral.md new file mode 100644 index 0000000000000000000000000000000000000000..97d205b3cc4ce1fdcc7acf310729592a3b7a5d0f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/dpm_discrete_ancestral.md @@ -0,0 +1,23 @@ + + +# KDPM2AncestralDiscreteScheduler + +The `KDPM2DiscreteScheduler` with ancestral sampling is inspired by the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper, and the scheduler is ported from and created by [Katherine Crowson](https://github.com/crowsonkb/). + +The original codebase can be found at [crowsonkb/k-diffusion](https://github.com/crowsonkb/k-diffusion). + +## KDPM2AncestralDiscreteScheduler +[[autodoc]] KDPM2AncestralDiscreteScheduler + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/dpm_sde.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/dpm_sde.md new file mode 100644 index 0000000000000000000000000000000000000000..fe87bb96ee17a27b6ca3d571f11e15d8af373359 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/dpm_sde.md @@ -0,0 +1,21 @@ + + +# DPMSolverSDEScheduler + +The `DPMSolverSDEScheduler` is inspired by the stochastic sampler from the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper, and the scheduler is ported from and created by [Katherine Crowson](https://github.com/crowsonkb/). + +## DPMSolverSDEScheduler +[[autodoc]] DPMSolverSDEScheduler + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/edm_euler.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/edm_euler.md new file mode 100644 index 0000000000000000000000000000000000000000..228f0505e3bc8e9763f735b0763127541d5faa61 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/edm_euler.md @@ -0,0 +1,22 @@ + + +# EDMEulerScheduler + +The Karras formulation of the Euler scheduler (Algorithm 2) from the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper by Karras et al. This is a fast scheduler which can often generate good outputs in 20-30 steps. The scheduler is based on the original [k-diffusion](https://github.com/crowsonkb/k-diffusion/blob/481677d114f6ea445aa009cf5bd7a9cdee909e47/k_diffusion/sampling.py#L51) implementation by [Katherine Crowson](https://github.com/crowsonkb/). + + +## EDMEulerScheduler +[[autodoc]] EDMEulerScheduler + +## EDMEulerSchedulerOutput +[[autodoc]] schedulers.scheduling_edm_euler.EDMEulerSchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/edm_multistep_dpm_solver.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/edm_multistep_dpm_solver.md new file mode 100644 index 0000000000000000000000000000000000000000..88ca639a924c7aeaddf621cef5ffcf37d8c8a6cc --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/edm_multistep_dpm_solver.md @@ -0,0 +1,24 @@ + + +# EDMDPMSolverMultistepScheduler + +`EDMDPMSolverMultistepScheduler` is a [Karras formulation](https://huggingface.co/papers/2206.00364) of `DPMSolverMultistepScheduler`, a multistep scheduler from [DPM-Solver: A Fast ODE Solver for Diffusion Probabilistic Model Sampling in Around 10 Steps](https://huggingface.co/papers/2206.00927) and [DPM-Solver++: Fast Solver for Guided Sampling of Diffusion Probabilistic Models](https://huggingface.co/papers/2211.01095) by Cheng Lu, Yuhao Zhou, Fan Bao, Jianfei Chen, Chongxuan Li, and Jun Zhu. + +DPMSolver (and the improved version DPMSolver++) is a fast dedicated high-order solver for diffusion ODEs with convergence order guarantee. Empirically, DPMSolver sampling with only 20 steps can generate high-quality +samples, and it can generate quite good samples even in 10 steps. + +## EDMDPMSolverMultistepScheduler +[[autodoc]] EDMDPMSolverMultistepScheduler + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/euler.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/euler.md new file mode 100644 index 0000000000000000000000000000000000000000..9c98118bd795d60c2c85faf6e7ba8cdfdae92575 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/euler.md @@ -0,0 +1,22 @@ + + +# EulerDiscreteScheduler + +The Euler scheduler (Algorithm 2) is from the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper by Karras et al. This is a fast scheduler which can often generate good outputs in 20-30 steps. The scheduler is based on the original [k-diffusion](https://github.com/crowsonkb/k-diffusion/blob/481677d114f6ea445aa009cf5bd7a9cdee909e47/k_diffusion/sampling.py#L51) implementation by [Katherine Crowson](https://github.com/crowsonkb/). + + +## EulerDiscreteScheduler +[[autodoc]] EulerDiscreteScheduler + +## EulerDiscreteSchedulerOutput +[[autodoc]] schedulers.scheduling_euler_discrete.EulerDiscreteSchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/euler_ancestral.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/euler_ancestral.md new file mode 100644 index 0000000000000000000000000000000000000000..eba9b063005affc741c37f7c7e42d741720795ca --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/euler_ancestral.md @@ -0,0 +1,21 @@ + + +# EulerAncestralDiscreteScheduler + +A scheduler that uses ancestral sampling with Euler method steps. This is a fast scheduler which can often generate good outputs in 20-30 steps. The scheduler is based on the original [k-diffusion](https://github.com/crowsonkb/k-diffusion/blob/481677d114f6ea445aa009cf5bd7a9cdee909e47/k_diffusion/sampling.py#L72) implementation by [Katherine Crowson](https://github.com/crowsonkb/). + +## EulerAncestralDiscreteScheduler +[[autodoc]] EulerAncestralDiscreteScheduler + +## EulerAncestralDiscreteSchedulerOutput +[[autodoc]] schedulers.scheduling_euler_ancestral_discrete.EulerAncestralDiscreteSchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/flow_match_euler_discrete.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/flow_match_euler_discrete.md new file mode 100644 index 0000000000000000000000000000000000000000..9e37932f4100d164467fe8edbb31489d9dbd6ac1 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/flow_match_euler_discrete.md @@ -0,0 +1,18 @@ + + +# FlowMatchEulerDiscreteScheduler + +`FlowMatchEulerDiscreteScheduler` is based on the flow-matching sampling introduced in [Stable Diffusion 3](https://huggingface.co/papers/2403.03206). + +## FlowMatchEulerDiscreteScheduler +[[autodoc]] FlowMatchEulerDiscreteScheduler diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/flow_match_heun_discrete.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/flow_match_heun_discrete.md new file mode 100644 index 0000000000000000000000000000000000000000..c3ca21f21374b198d95a86bdc145757483a53cab --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/flow_match_heun_discrete.md @@ -0,0 +1,18 @@ + + +# FlowMatchHeunDiscreteScheduler + +`FlowMatchHeunDiscreteScheduler` is based on the flow-matching sampling introduced in [EDM](https://huggingface.co/papers/2403.03206). + +## FlowMatchHeunDiscreteScheduler +[[autodoc]] FlowMatchHeunDiscreteScheduler diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/heun.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/heun.md new file mode 100644 index 0000000000000000000000000000000000000000..bca5cf743d05ab8a96fee62473627bf7af4cf7fc --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/heun.md @@ -0,0 +1,21 @@ + + +# HeunDiscreteScheduler + +The Heun scheduler (Algorithm 1) is from the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) paper by Karras et al. The scheduler is ported from the [k-diffusion](https://github.com/crowsonkb/k-diffusion) library and created by [Katherine Crowson](https://github.com/crowsonkb/). + +## HeunDiscreteScheduler +[[autodoc]] HeunDiscreteScheduler + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ipndm.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ipndm.md new file mode 100644 index 0000000000000000000000000000000000000000..eeeee8aea32eb56767ad3f00d1cea661c81644c4 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/ipndm.md @@ -0,0 +1,21 @@ + + +# IPNDMScheduler + +`IPNDMScheduler` is a fourth-order Improved Pseudo Linear Multistep scheduler. The original implementation can be found at [crowsonkb/v-diffusion-pytorch](https://github.com/crowsonkb/v-diffusion-pytorch/blob/987f8985e38208345c1959b0ea767a625831cc9b/diffusion/sampling.py#L296). + +## IPNDMScheduler +[[autodoc]] IPNDMScheduler + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/lcm.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/lcm.md new file mode 100644 index 0000000000000000000000000000000000000000..3c06063e8a680b1bd2b7559a999520bc656bcb7f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/lcm.md @@ -0,0 +1,21 @@ + + +# Latent Consistency Model Multistep Scheduler + +## Overview + +Multistep and onestep scheduler (Algorithm 3) introduced alongside latent consistency models in the paper [Latent Consistency Models: Synthesizing High-Resolution Images with Few-Step Inference](https://huggingface.co/papers/2310.04378) by Simian Luo, Yiqin Tan, Longbo Huang, Jian Li, and Hang Zhao. +This scheduler should be able to generate good samples from [`LatentConsistencyModelPipeline`] in 1-8 steps. + +## LCMScheduler +[[autodoc]] LCMScheduler diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/lms_discrete.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/lms_discrete.md new file mode 100644 index 0000000000000000000000000000000000000000..a0f4aea8a79077f8f3cdd6833c198c63925ee138 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/lms_discrete.md @@ -0,0 +1,21 @@ + + +# LMSDiscreteScheduler + +`LMSDiscreteScheduler` is a linear multistep scheduler for discrete beta schedules. The scheduler is ported from and created by [Katherine Crowson](https://github.com/crowsonkb/), and the original implementation can be found at [crowsonkb/k-diffusion](https://github.com/crowsonkb/k-diffusion/blob/481677d114f6ea445aa009cf5bd7a9cdee909e47/k_diffusion/sampling.py#L181). + +## LMSDiscreteScheduler +[[autodoc]] LMSDiscreteScheduler + +## LMSDiscreteSchedulerOutput +[[autodoc]] schedulers.scheduling_lms_discrete.LMSDiscreteSchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/multistep_dpm_solver.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/multistep_dpm_solver.md new file mode 100644 index 0000000000000000000000000000000000000000..ff6e5688e24ff7f1a7e46357431572808b5eee16 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/multistep_dpm_solver.md @@ -0,0 +1,35 @@ + + +# DPMSolverMultistepScheduler + +`DPMSolverMultistepScheduler` is a multistep scheduler from [DPM-Solver: A Fast ODE Solver for Diffusion Probabilistic Model Sampling in Around 10 Steps](https://huggingface.co/papers/2206.00927) and [DPM-Solver++: Fast Solver for Guided Sampling of Diffusion Probabilistic Models](https://huggingface.co/papers/2211.01095) by Cheng Lu, Yuhao Zhou, Fan Bao, Jianfei Chen, Chongxuan Li, and Jun Zhu. + +DPMSolver (and the improved version DPMSolver++) is a fast dedicated high-order solver for diffusion ODEs with convergence order guarantee. Empirically, DPMSolver sampling with only 20 steps can generate high-quality +samples, and it can generate quite good samples even in 10 steps. + +## Tips + +It is recommended to set `solver_order` to 2 for guide sampling, and `solver_order=3` for unconditional sampling. + +Dynamic thresholding from [Imagen](https://huggingface.co/papers/2205.11487) is supported, and for pixel-space +diffusion models, you can set both `algorithm_type="dpmsolver++"` and `thresholding=True` to use the dynamic +thresholding. This thresholding method is unsuitable for latent-space diffusion models such as +Stable Diffusion. + +The SDE variant of DPMSolver and DPM-Solver++ is also supported, but only for the first and second-order solvers. This is a fast SDE solver for the reverse diffusion SDE. It is recommended to use the second-order `sde-dpmsolver++`. + +## DPMSolverMultistepScheduler +[[autodoc]] DPMSolverMultistepScheduler + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/multistep_dpm_solver_cogvideox.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/multistep_dpm_solver_cogvideox.md new file mode 100644 index 0000000000000000000000000000000000000000..bce09a15f543d4ba181dd60275ac856097b03bfa --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/multistep_dpm_solver_cogvideox.md @@ -0,0 +1,19 @@ + + +# CogVideoXDPMScheduler + +`CogVideoXDPMScheduler` is based on [DPM-Solver: A Fast ODE Solver for Diffusion Probabilistic Model Sampling in Around 10 Steps](https://huggingface.co/papers/2206.00927) and [DPM-Solver++: Fast Solver for Guided Sampling of Diffusion Probabilistic Models](https://huggingface.co/papers/2211.01095), specifically for CogVideoX models. + +## CogVideoXDPMScheduler + +[[autodoc]] CogVideoXDPMScheduler diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/multistep_dpm_solver_inverse.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/multistep_dpm_solver_inverse.md new file mode 100644 index 0000000000000000000000000000000000000000..b77a5cf1407963e0ea7ead0f176b97141c0df1f8 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/multistep_dpm_solver_inverse.md @@ -0,0 +1,30 @@ + + +# DPMSolverMultistepInverse + +`DPMSolverMultistepInverse` is the inverted scheduler from [DPM-Solver: A Fast ODE Solver for Diffusion Probabilistic Model Sampling in Around 10 Steps](https://huggingface.co/papers/2206.00927) and [DPM-Solver++: Fast Solver for Guided Sampling of Diffusion Probabilistic Models](https://huggingface.co/papers/2211.01095) by Cheng Lu, Yuhao Zhou, Fan Bao, Jianfei Chen, Chongxuan Li, and Jun Zhu. + +The implementation is mostly based on the DDIM inversion definition of [Null-text Inversion for Editing Real Images using Guided Diffusion Models](https://huggingface.co/papers/2211.09794) and notebook implementation of the [`DiffEdit`] latent inversion from [Xiang-cd/DiffEdit-stable-diffusion](https://github.com/Xiang-cd/DiffEdit-stable-diffusion/blob/main/diffedit.ipynb). + +## Tips + +Dynamic thresholding from [Imagen](https://huggingface.co/papers/2205.11487) is supported, and for pixel-space +diffusion models, you can set both `algorithm_type="dpmsolver++"` and `thresholding=True` to use the dynamic +thresholding. This thresholding method is unsuitable for latent-space diffusion models such as +Stable Diffusion. + +## DPMSolverMultistepInverseScheduler +[[autodoc]] DPMSolverMultistepInverseScheduler + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/overview.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/overview.md new file mode 100644 index 0000000000000000000000000000000000000000..af287454e15d4f205ccf8c2f5d5934b6710f7f08 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/overview.md @@ -0,0 +1,73 @@ + + +# Schedulers + +🤗 Diffusers provides many scheduler functions for the diffusion process. A scheduler takes a model's output (the sample which the diffusion process is iterating on) and a timestep to return a denoised sample. The timestep is important because it dictates where in the diffusion process the step is; data is generated by iterating forward *n* timesteps and inference occurs by propagating backward through the timesteps. Based on the timestep, a scheduler may be *discrete* in which case the timestep is an `int` or *continuous* in which case the timestep is a `float`. + +Depending on the context, a scheduler defines how to iteratively add noise to an image or how to update a sample based on a model's output: + +- during *training*, a scheduler adds noise (there are different algorithms for how to add noise) to a sample to train a diffusion model +- during *inference*, a scheduler defines how to update a sample based on a pretrained model's output + +Many schedulers are implemented from the [k-diffusion](https://github.com/crowsonkb/k-diffusion) library by [Katherine Crowson](https://github.com/crowsonkb/), and they're also widely used in A1111. To help you map the schedulers from k-diffusion and A1111 to the schedulers in 🤗 Diffusers, take a look at the table below: + +| A1111/k-diffusion | 🤗 Diffusers | Usage | +|---------------------|-------------------------------------|---------------------------------------------------------------------------------------------------------------| +| DPM++ 2M | [`DPMSolverMultistepScheduler`] | | +| DPM++ 2M Karras | [`DPMSolverMultistepScheduler`] | init with `use_karras_sigmas=True` | +| DPM++ 2M SDE | [`DPMSolverMultistepScheduler`] | init with `algorithm_type="sde-dpmsolver++"` | +| DPM++ 2M SDE Karras | [`DPMSolverMultistepScheduler`] | init with `use_karras_sigmas=True` and `algorithm_type="sde-dpmsolver++"` | +| DPM++ 2S a | N/A | very similar to `DPMSolverSinglestepScheduler` | +| DPM++ 2S a Karras | N/A | very similar to `DPMSolverSinglestepScheduler(use_karras_sigmas=True, ...)` | +| DPM++ SDE | [`DPMSolverSinglestepScheduler`] | | +| DPM++ SDE Karras | [`DPMSolverSinglestepScheduler`] | init with `use_karras_sigmas=True` | +| DPM2 | [`KDPM2DiscreteScheduler`] | | +| DPM2 Karras | [`KDPM2DiscreteScheduler`] | init with `use_karras_sigmas=True` | +| DPM2 a | [`KDPM2AncestralDiscreteScheduler`] | | +| DPM2 a Karras | [`KDPM2AncestralDiscreteScheduler`] | init with `use_karras_sigmas=True` | +| DPM adaptive | N/A | | +| DPM fast | N/A | | +| Euler | [`EulerDiscreteScheduler`] | | +| Euler a | [`EulerAncestralDiscreteScheduler`] | | +| Heun | [`HeunDiscreteScheduler`] | | +| LMS | [`LMSDiscreteScheduler`] | | +| LMS Karras | [`LMSDiscreteScheduler`] | init with `use_karras_sigmas=True` | +| N/A | [`DEISMultistepScheduler`] | | +| N/A | [`UniPCMultistepScheduler`] | | + +## Noise schedules and schedule types +| A1111/k-diffusion | 🤗 Diffusers | +|--------------------------|----------------------------------------------------------------------------| +| Karras | init with `use_karras_sigmas=True` | +| sgm_uniform | init with `timestep_spacing="trailing"` | +| simple | init with `timestep_spacing="trailing"` | +| exponential | init with `timestep_spacing="linspace"`, `use_exponential_sigmas=True` | +| beta | init with `timestep_spacing="linspace"`, `use_beta_sigmas=True` | + +All schedulers are built from the base [`SchedulerMixin`] class which implements low level utilities shared by all schedulers. + +## SchedulerMixin +[[autodoc]] SchedulerMixin + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput + +## KarrasDiffusionSchedulers + +[`KarrasDiffusionSchedulers`] are a broad generalization of schedulers in 🤗 Diffusers. The schedulers in this class are distinguished at a high level by their noise sampling strategy, the type of network and scaling, the training strategy, and how the loss is weighed. + +The different schedulers in this class, depending on the ordinary differential equations (ODE) solver type, fall into the above taxonomy and provide a good abstraction for the design of the main schedulers implemented in 🤗 Diffusers. The schedulers in this class are given [here](https://github.com/huggingface/diffusers/blob/a69754bb879ed55b9b6dc9dd0b3cf4fa4124c765/src/diffusers/schedulers/scheduling_utils.py#L32). + +## PushToHubMixin + +[[autodoc]] utils.PushToHubMixin diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/pndm.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/pndm.md new file mode 100644 index 0000000000000000000000000000000000000000..ed959d53e0262004ff8d7b8818fcf23981a932be --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/pndm.md @@ -0,0 +1,21 @@ + + +# PNDMScheduler + +`PNDMScheduler`, or pseudo numerical methods for diffusion models, uses more advanced ODE integration techniques like the Runge-Kutta and linear multi-step method. The original implementation can be found at [crowsonkb/k-diffusion](https://github.com/crowsonkb/k-diffusion/blob/481677d114f6ea445aa009cf5bd7a9cdee909e47/k_diffusion/sampling.py#L181). + +## PNDMScheduler +[[autodoc]] PNDMScheduler + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/repaint.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/repaint.md new file mode 100644 index 0000000000000000000000000000000000000000..3b19e344a0bf3e252c7521e00737f5ada22fe15f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/repaint.md @@ -0,0 +1,27 @@ + + +# RePaintScheduler + +`RePaintScheduler` is a DDPM-based inpainting scheduler for unsupervised inpainting with extreme masks. It is designed to be used with the [`RePaintPipeline`], and it is based on the paper [RePaint: Inpainting using Denoising Diffusion Probabilistic Models](https://huggingface.co/papers/2201.09865) by Andreas Lugmayr et al. + +The abstract from the paper is: + +*Free-form inpainting is the task of adding new content to an image in the regions specified by an arbitrary binary mask. Most existing approaches train for a certain distribution of masks, which limits their generalization capabilities to unseen mask types. Furthermore, training with pixel-wise and perceptual losses often leads to simple textural extensions towards the missing areas instead of semantically meaningful generation. In this work, we propose RePaint: A Denoising Diffusion Probabilistic Model (DDPM) based inpainting approach that is applicable to even extreme masks. We employ a pretrained unconditional DDPM as the generative prior. To condition the generation process, we only alter the reverse diffusion iterations by sampling the unmasked regions using the given image information. Since this technique does not modify or condition the original DDPM network itself, the model produces high-quality and diverse output images for any inpainting form. We validate our method for both faces and general-purpose image inpainting using standard and extreme masks. RePaint outperforms state-of-the-art Autoregressive, and GAN approaches for at least five out of six mask distributions. GitHub Repository: [this http URL](http://git.io/RePaint).* + +The original implementation can be found at [andreas128/RePaint](https://github.com/andreas128/). + +## RePaintScheduler +[[autodoc]] RePaintScheduler + +## RePaintSchedulerOutput +[[autodoc]] schedulers.scheduling_repaint.RePaintSchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/score_sde_ve.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/score_sde_ve.md new file mode 100644 index 0000000000000000000000000000000000000000..43bce146be84a3091af6caf094d129a933a52b87 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/score_sde_ve.md @@ -0,0 +1,25 @@ + + +# ScoreSdeVeScheduler + +`ScoreSdeVeScheduler` is a variance exploding stochastic differential equation (SDE) scheduler. It was introduced in the [Score-Based Generative Modeling through Stochastic Differential Equations](https://huggingface.co/papers/2011.13456) paper by Yang Song, Jascha Sohl-Dickstein, Diederik P. Kingma, Abhishek Kumar, Stefano Ermon, Ben Poole. + +The abstract from the paper is: + +*Creating noise from data is easy; creating data from noise is generative modeling. We present a stochastic differential equation (SDE) that smoothly transforms a complex data distribution to a known prior distribution by slowly injecting noise, and a corresponding reverse-time SDE that transforms the prior distribution back into the data distribution by slowly removing the noise. Crucially, the reverse-time SDE depends only on the time-dependent gradient field (\aka, score) of the perturbed data distribution. By leveraging advances in score-based generative modeling, we can accurately estimate these scores with neural networks, and use numerical SDE solvers to generate samples. We show that this framework encapsulates previous approaches in score-based generative modeling and diffusion probabilistic modeling, allowing for new sampling procedures and new modeling capabilities. In particular, we introduce a predictor-corrector framework to correct errors in the evolution of the discretized reverse-time SDE. We also derive an equivalent neural ODE that samples from the same distribution as the SDE, but additionally enables exact likelihood computation, and improved sampling efficiency. In addition, we provide a new way to solve inverse problems with score-based models, as demonstrated with experiments on class-conditional generation, image inpainting, and colorization. Combined with multiple architectural improvements, we achieve record-breaking performance for unconditional image generation on CIFAR-10 with an Inception score of 9.89 and FID of 2.20, a competitive likelihood of 2.99 bits/dim, and demonstrate high fidelity generation of 1024 x 1024 images for the first time from a score-based generative model.* + +## ScoreSdeVeScheduler +[[autodoc]] ScoreSdeVeScheduler + +## SdeVeOutput +[[autodoc]] schedulers.scheduling_sde_ve.SdeVeOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/score_sde_vp.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/score_sde_vp.md new file mode 100644 index 0000000000000000000000000000000000000000..4b25b259708a6b72714806b5c90bc23d31444242 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/score_sde_vp.md @@ -0,0 +1,28 @@ + + +# ScoreSdeVpScheduler + +`ScoreSdeVpScheduler` is a variance preserving stochastic differential equation (SDE) scheduler. It was introduced in the [Score-Based Generative Modeling through Stochastic Differential Equations](https://huggingface.co/papers/2011.13456) paper by Yang Song, Jascha Sohl-Dickstein, Diederik P. Kingma, Abhishek Kumar, Stefano Ermon, Ben Poole. + +The abstract from the paper is: + +*Creating noise from data is easy; creating data from noise is generative modeling. We present a stochastic differential equation (SDE) that smoothly transforms a complex data distribution to a known prior distribution by slowly injecting noise, and a corresponding reverse-time SDE that transforms the prior distribution back into the data distribution by slowly removing the noise. Crucially, the reverse-time SDE depends only on the time-dependent gradient field (\aka, score) of the perturbed data distribution. By leveraging advances in score-based generative modeling, we can accurately estimate these scores with neural networks, and use numerical SDE solvers to generate samples. We show that this framework encapsulates previous approaches in score-based generative modeling and diffusion probabilistic modeling, allowing for new sampling procedures and new modeling capabilities. In particular, we introduce a predictor-corrector framework to correct errors in the evolution of the discretized reverse-time SDE. We also derive an equivalent neural ODE that samples from the same distribution as the SDE, but additionally enables exact likelihood computation, and improved sampling efficiency. In addition, we provide a new way to solve inverse problems with score-based models, as demonstrated with experiments on class-conditional generation, image inpainting, and colorization. Combined with multiple architectural improvements, we achieve record-breaking performance for unconditional image generation on CIFAR-10 with an Inception score of 9.89 and FID of 2.20, a competitive likelihood of 2.99 bits/dim, and demonstrate high fidelity generation of 1024 x 1024 images for the first time from a score-based generative model.* + + + +🚧 This scheduler is under construction! + + + +## ScoreSdeVpScheduler +[[autodoc]] schedulers.deprecated.scheduling_sde_vp.ScoreSdeVpScheduler diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/singlestep_dpm_solver.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/singlestep_dpm_solver.md new file mode 100644 index 0000000000000000000000000000000000000000..063678f5cfb29f4f6de4960ca2889a1d78d7033b --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/singlestep_dpm_solver.md @@ -0,0 +1,35 @@ + + +# DPMSolverSinglestepScheduler + +`DPMSolverSinglestepScheduler` is a single step scheduler from [DPM-Solver: A Fast ODE Solver for Diffusion Probabilistic Model Sampling in Around 10 Steps](https://huggingface.co/papers/2206.00927) and [DPM-Solver++: Fast Solver for Guided Sampling of Diffusion Probabilistic Models](https://huggingface.co/papers/2211.01095) by Cheng Lu, Yuhao Zhou, Fan Bao, Jianfei Chen, Chongxuan Li, and Jun Zhu. + +DPMSolver (and the improved version DPMSolver++) is a fast dedicated high-order solver for diffusion ODEs with convergence order guarantee. Empirically, DPMSolver sampling with only 20 steps can generate high-quality +samples, and it can generate quite good samples even in 10 steps. + +The original implementation can be found at [LuChengTHU/dpm-solver](https://github.com/LuChengTHU/dpm-solver). + +## Tips + +It is recommended to set `solver_order` to 2 for guide sampling, and `solver_order=3` for unconditional sampling. + +Dynamic thresholding from [Imagen](https://huggingface.co/papers/2205.11487) is supported, and for pixel-space +diffusion models, you can set both `algorithm_type="dpmsolver++"` and `thresholding=True` to use dynamic +thresholding. This thresholding method is unsuitable for latent-space diffusion models such as +Stable Diffusion. + +## DPMSolverSinglestepScheduler +[[autodoc]] DPMSolverSinglestepScheduler + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/stochastic_karras_ve.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/stochastic_karras_ve.md new file mode 100644 index 0000000000000000000000000000000000000000..2d08b3289c95a1ff47bf9b3c4b64cfc41f939814 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/stochastic_karras_ve.md @@ -0,0 +1,21 @@ + + +# KarrasVeScheduler + +`KarrasVeScheduler` is a stochastic sampler tailored to variance-expanding (VE) models. It is based on the [Elucidating the Design Space of Diffusion-Based Generative Models](https://huggingface.co/papers/2206.00364) and [Score-based generative modeling through stochastic differential equations](https://huggingface.co/papers/2011.13456) papers. + +## KarrasVeScheduler +[[autodoc]] KarrasVeScheduler + +## KarrasVeOutput +[[autodoc]] schedulers.deprecated.scheduling_karras_ve.KarrasVeOutput \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/tcd.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/tcd.md new file mode 100644 index 0000000000000000000000000000000000000000..27fc111d644a5065a36f1cffdfcc487f1b4e8d2d --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/tcd.md @@ -0,0 +1,29 @@ + + +# TCDScheduler + +[Trajectory Consistency Distillation](https://huggingface.co/papers/2402.19159) by Jianbin Zheng, Minghui Hu, Zhongyi Fan, Chaoyue Wang, Changxing Ding, Dacheng Tao and Tat-Jen Cham introduced a Strategic Stochastic Sampling (Algorithm 4) that is capable of generating good samples in a small number of steps. Distinguishing it as an advanced iteration of the multistep scheduler (Algorithm 1) in the [Consistency Models](https://huggingface.co/papers/2303.01469), Strategic Stochastic Sampling specifically tailored for the trajectory consistency function. + +The abstract from the paper is: + +*Latent Consistency Model (LCM) extends the Consistency Model to the latent space and leverages the guided consistency distillation technique to achieve impressive performance in accelerating text-to-image synthesis. However, we observed that LCM struggles to generate images with both clarity and detailed intricacy. To address this limitation, we initially delve into and elucidate the underlying causes. Our investigation identifies that the primary issue stems from errors in three distinct areas. Consequently, we introduce Trajectory Consistency Distillation (TCD), which encompasses trajectory consistency function and strategic stochastic sampling. The trajectory consistency function diminishes the distillation errors by broadening the scope of the self-consistency boundary condition and endowing the TCD with the ability to accurately trace the entire trajectory of the Probability Flow ODE. Additionally, strategic stochastic sampling is specifically designed to circumvent the accumulated errors inherent in multi-step consistency sampling, which is meticulously tailored to complement the TCD model. Experiments demonstrate that TCD not only significantly enhances image quality at low NFEs but also yields more detailed results compared to the teacher model at high NFEs.* + +The original codebase can be found at [jabir-zheng/TCD](https://github.com/jabir-zheng/TCD). + +## TCDScheduler +[[autodoc]] TCDScheduler + + +## TCDSchedulerOutput +[[autodoc]] schedulers.scheduling_tcd.TCDSchedulerOutput + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/unipc.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/unipc.md new file mode 100644 index 0000000000000000000000000000000000000000..d82345996fba60eb07cb1fd947923e6b75d6cdae --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/unipc.md @@ -0,0 +1,35 @@ + + +# UniPCMultistepScheduler + +`UniPCMultistepScheduler` is a training-free framework designed for fast sampling of diffusion models. It was introduced in [UniPC: A Unified Predictor-Corrector Framework for Fast Sampling of Diffusion Models](https://huggingface.co/papers/2302.04867) by Wenliang Zhao, Lujia Bai, Yongming Rao, Jie Zhou, Jiwen Lu. + +It consists of a corrector (UniC) and a predictor (UniP) that share a unified analytical form and support arbitrary orders. +UniPC is by design model-agnostic, supporting pixel-space/latent-space DPMs on unconditional/conditional sampling. It can also be applied to both noise prediction and data prediction models. The corrector UniC can be also applied after any off-the-shelf solvers to increase the order of accuracy. + +The abstract from the paper is: + +*Diffusion probabilistic models (DPMs) have demonstrated a very promising ability in high-resolution image synthesis. However, sampling from a pre-trained DPM is time-consuming due to the multiple evaluations of the denoising network, making it more and more important to accelerate the sampling of DPMs. Despite recent progress in designing fast samplers, existing methods still cannot generate satisfying images in many applications where fewer steps (e.g., <10) are favored. In this paper, we develop a unified corrector (UniC) that can be applied after any existing DPM sampler to increase the order of accuracy without extra model evaluations, and derive a unified predictor (UniP) that supports arbitrary order as a byproduct. Combining UniP and UniC, we propose a unified predictor-corrector framework called UniPC for the fast sampling of DPMs, which has a unified analytical form for any order and can significantly improve the sampling quality over previous methods, especially in extremely few steps. We evaluate our methods through extensive experiments including both unconditional and conditional sampling using pixel-space and latent-space DPMs. Our UniPC can achieve 3.87 FID on CIFAR10 (unconditional) and 7.51 FID on ImageNet 256×256 (conditional) with only 10 function evaluations. Code is available at [this https URL](https://github.com/wl-zhao/UniPC).* + +## Tips + +It is recommended to set `solver_order` to 2 for guide sampling, and `solver_order=3` for unconditional sampling. + +Dynamic thresholding from [Imagen](https://huggingface.co/papers/2205.11487) is supported, and for pixel-space +diffusion models, you can set both `predict_x0=True` and `thresholding=True` to use dynamic thresholding. This thresholding method is unsuitable for latent-space diffusion models such as Stable Diffusion. + +## UniPCMultistepScheduler +[[autodoc]] UniPCMultistepScheduler + +## SchedulerOutput +[[autodoc]] schedulers.scheduling_utils.SchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/vq_diffusion.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/vq_diffusion.md new file mode 100644 index 0000000000000000000000000000000000000000..b21cba9ee5ae7311476f14430c6523c96e7ed752 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/schedulers/vq_diffusion.md @@ -0,0 +1,25 @@ + + +# VQDiffusionScheduler + +`VQDiffusionScheduler` converts the transformer model's output into a sample for the unnoised image at the previous diffusion timestep. It was introduced in [Vector Quantized Diffusion Model for Text-to-Image Synthesis](https://huggingface.co/papers/2111.14822) by Shuyang Gu, Dong Chen, Jianmin Bao, Fang Wen, Bo Zhang, Dongdong Chen, Lu Yuan, Baining Guo. + +The abstract from the paper is: + +*We present the vector quantized diffusion (VQ-Diffusion) model for text-to-image generation. This method is based on a vector quantized variational autoencoder (VQ-VAE) whose latent space is modeled by a conditional variant of the recently developed Denoising Diffusion Probabilistic Model (DDPM). We find that this latent-space method is well-suited for text-to-image generation tasks because it not only eliminates the unidirectional bias with existing methods but also allows us to incorporate a mask-and-replace diffusion strategy to avoid the accumulation of errors, which is a serious problem with existing methods. Our experiments show that the VQ-Diffusion produces significantly better text-to-image generation results when compared with conventional autoregressive (AR) models with similar numbers of parameters. Compared with previous GAN-based text-to-image methods, our VQ-Diffusion can handle more complex scenes and improve the synthesized image quality by a large margin. Finally, we show that the image generation computation in our method can be made highly efficient by reparameterization. With traditional AR methods, the text-to-image generation time increases linearly with the output image resolution and hence is quite time consuming even for normal size images. The VQ-Diffusion allows us to achieve a better trade-off between quality and speed. Our experiments indicate that the VQ-Diffusion model with the reparameterization is fifteen times faster than traditional AR methods while achieving a better image quality.* + +## VQDiffusionScheduler +[[autodoc]] VQDiffusionScheduler + +## VQDiffusionSchedulerOutput +[[autodoc]] schedulers.scheduling_vq_diffusion.VQDiffusionSchedulerOutput diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/utilities.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/utilities.md new file mode 100644 index 0000000000000000000000000000000000000000..b653cdafbb28c529ee2182f5eb20e94b2ba22b2c --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/utilities.md @@ -0,0 +1,51 @@ + + +# Utilities + +Utility and helper functions for working with 🤗 Diffusers. + +## numpy_to_pil + +[[autodoc]] utils.numpy_to_pil + +## pt_to_pil + +[[autodoc]] utils.pt_to_pil + +## load_image + +[[autodoc]] utils.load_image + +## export_to_gif + +[[autodoc]] utils.export_to_gif + +## export_to_video + +[[autodoc]] utils.export_to_video + +## make_image_grid + +[[autodoc]] utils.make_image_grid + +## randn_tensor + +[[autodoc]] utils.torch_utils.randn_tensor + +## apply_layerwise_casting + +[[autodoc]] hooks.layerwise_casting.apply_layerwise_casting + +## apply_group_offloading + +[[autodoc]] hooks.group_offloading.apply_group_offloading diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/video_processor.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/video_processor.md new file mode 100644 index 0000000000000000000000000000000000000000..6461c46c286f14fcbb142859a33ad3675ee10a54 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/api/video_processor.md @@ -0,0 +1,21 @@ + + +# Video Processor + +The [`VideoProcessor`] provides a unified API for video pipelines to prepare inputs for VAE encoding and post-processing outputs once they're decoded. The class inherits [`VaeImageProcessor`] so it includes transformations such as resizing, normalization, and conversion between PIL Image, PyTorch, and NumPy arrays. + +## VideoProcessor + +[[autodoc]] video_processor.VideoProcessor.preprocess_video + +[[autodoc]] video_processor.VideoProcessor.postprocess_video diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/community_projects.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/community_projects.md new file mode 100644 index 0000000000000000000000000000000000000000..2a00a9f44dfcf6ac655334b20f66b58a420bd680 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/community_projects.md @@ -0,0 +1,90 @@ + + +# Community Projects + +Welcome to Community Projects. This space is dedicated to showcasing the incredible work and innovative applications created by our vibrant community using the `diffusers` library. + +This section aims to: + +- Highlight diverse and inspiring projects built with `diffusers` +- Foster knowledge sharing within our community +- Provide real-world examples of how `diffusers` can be leveraged + +Happy exploring, and thank you for being part of the Diffusers community! + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + + +
Project NameDescription
dream-textures Stable Diffusion built-in to Blender
HiDiffusion Increases the resolution and speed of your diffusion model by only adding a single line of code
IC-Light IC-Light is a project to manipulate the illumination of images
InstantID InstantID : Zero-shot Identity-Preserving Generation in Seconds
IOPaint Image inpainting tool powered by SOTA AI Model. Remove any unwanted object, defect, people from your pictures or erase and replace(powered by stable diffusion) any thing on your pictures.
Kohya Gradio GUI for Kohya's Stable Diffusion trainers
MagicAnimate MagicAnimate: Temporally Consistent Human Image Animation using Diffusion Model
OOTDiffusion Outfitting Fusion based Latent Diffusion for Controllable Virtual Try-on
SD.Next SD.Next: Advanced Implementation of Stable Diffusion and other Diffusion-based generative image models
stable-dreamfusion Text-to-3D & Image-to-3D & Mesh Exportation with NeRF + Diffusion
StoryDiffusion StoryDiffusion can create a magic story by generating consistent images and videos.
StreamDiffusion A Pipeline-Level Solution for Real-Time Interactive Generation
Stable Diffusion Server A server configured for Inpainting/Generation/img2img with one stable diffusion model
Model Search Search models on Civitai and Hugging Face
Skrample Fully modular scheduler functions with 1st class diffusers integration.
diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/conceptual/contribution.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/conceptual/contribution.md new file mode 100644 index 0000000000000000000000000000000000000000..b4d33cb5e39cf43f4c99735600f5d8aa951d2b84 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/conceptual/contribution.md @@ -0,0 +1,568 @@ + + +# How to contribute to Diffusers 🧨 + +We ❤️ contributions from the open-source community! Everyone is welcome, and all types of participation –not just code– are valued and appreciated. Answering questions, helping others, reaching out, and improving the documentation are all immensely valuable to the community, so don't be afraid and get involved if you're up for it! + +Everyone is encouraged to start by saying 👋 in our public Discord channel. We discuss the latest trends in diffusion models, ask questions, show off personal projects, help each other with contributions, or just hang out ☕. Join us on Discord + +Whichever way you choose to contribute, we strive to be part of an open, welcoming, and kind community. Please, read our [code of conduct](https://github.com/huggingface/diffusers/blob/main/CODE_OF_CONDUCT.md) and be mindful to respect it during your interactions. We also recommend you become familiar with the [ethical guidelines](https://huggingface.co/docs/diffusers/conceptual/ethical_guidelines) that guide our project and ask you to adhere to the same principles of transparency and responsibility. + +We enormously value feedback from the community, so please do not be afraid to speak up if you believe you have valuable feedback that can help improve the library - every message, comment, issue, and pull request (PR) is read and considered. + +## Overview + +You can contribute in many ways ranging from answering questions on issues and discussions to adding new diffusion models to the core library. + +In the following, we give an overview of different ways to contribute, ranked by difficulty in ascending order. All of them are valuable to the community. + +* 1. Asking and answering questions on [the Diffusers discussion forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers) or on [Discord](https://discord.gg/G7tWnz98XR). +* 2. Opening new issues on [the GitHub Issues tab](https://github.com/huggingface/diffusers/issues/new/choose) or new discussions on [the GitHub Discussions tab](https://github.com/huggingface/diffusers/discussions/new/choose). +* 3. Answering issues on [the GitHub Issues tab](https://github.com/huggingface/diffusers/issues) or discussions on [the GitHub Discussions tab](https://github.com/huggingface/diffusers/discussions). +* 4. Fix a simple issue, marked by the "Good first issue" label, see [here](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22). +* 5. Contribute to the [documentation](https://github.com/huggingface/diffusers/tree/main/docs/source). +* 6. Contribute a [Community Pipeline](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3Acommunity-examples). +* 7. Contribute to the [examples](https://github.com/huggingface/diffusers/tree/main/examples). +* 8. Fix a more difficult issue, marked by the "Good second issue" label, see [here](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22Good+second+issue%22). +* 9. Add a new pipeline, model, or scheduler, see ["New Pipeline/Model"](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+pipeline%2Fmodel%22) and ["New scheduler"](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+scheduler%22) issues. For this contribution, please have a look at [Design Philosophy](https://github.com/huggingface/diffusers/blob/main/PHILOSOPHY.md). + +As said before, **all contributions are valuable to the community**. +In the following, we will explain each contribution a bit more in detail. + +For all contributions 4 - 9, you will need to open a PR. It is explained in detail how to do so in [Opening a pull request](#how-to-open-a-pr). + +### 1. Asking and answering questions on the Diffusers discussion forum or on the Diffusers Discord + +Any question or comment related to the Diffusers library can be asked on the [discussion forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/) or on [Discord](https://discord.gg/G7tWnz98XR). Such questions and comments include (but are not limited to): +- Reports of training or inference experiments in an attempt to share knowledge +- Presentation of personal projects +- Questions to non-official training examples +- Project proposals +- General feedback +- Paper summaries +- Asking for help on personal projects that build on top of the Diffusers library +- General questions +- Ethical questions regarding diffusion models +- ... + +Every question that is asked on the forum or on Discord actively encourages the community to publicly +share knowledge and might very well help a beginner in the future who has the same question you're +having. Please do pose any questions you might have. +In the same spirit, you are of immense help to the community by answering such questions because this way you are publicly documenting knowledge for everybody to learn from. + +**Please** keep in mind that the more effort you put into asking or answering a question, the higher +the quality of the publicly documented knowledge. In the same way, well-posed and well-answered questions create a high-quality knowledge database accessible to everybody, while badly posed questions or answers reduce the overall quality of the public knowledge database. +In short, a high quality question or answer is *precise*, *concise*, *relevant*, *easy-to-understand*, *accessible*, and *well-formatted/well-posed*. For more information, please have a look through the [How to write a good issue](#how-to-write-a-good-issue) section. + +**NOTE about channels**: +[*The forum*](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) is much better indexed by search engines, such as Google. Posts are ranked by popularity rather than chronologically. Hence, it's easier to look up questions and answers that we posted some time ago. +In addition, questions and answers posted in the forum can easily be linked to. +In contrast, *Discord* has a chat-like format that invites fast back-and-forth communication. +While it will most likely take less time for you to get an answer to your question on Discord, your +question won't be visible anymore over time. Also, it's much harder to find information that was posted a while back on Discord. We therefore strongly recommend using the forum for high-quality questions and answers in an attempt to create long-lasting knowledge for the community. If discussions on Discord lead to very interesting answers and conclusions, we recommend posting the results on the forum to make the information more available for future readers. + +### 2. Opening new issues on the GitHub issues tab + +The 🧨 Diffusers library is robust and reliable thanks to the users who notify us of +the problems they encounter. So thank you for reporting an issue. + +Remember, GitHub issues are reserved for technical questions directly related to the Diffusers library, bug reports, feature requests, or feedback on the library design. + +In a nutshell, this means that everything that is **not** related to the **code of the Diffusers library** (including the documentation) should **not** be asked on GitHub, but rather on either the [forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) or [Discord](https://discord.gg/G7tWnz98XR). + +**Please consider the following guidelines when opening a new issue**: +- Make sure you have searched whether your issue has already been asked before (use the search bar on GitHub under Issues). +- Please never report a new issue on another (related) issue. If another issue is highly related, please +open a new issue nevertheless and link to the related issue. +- Make sure your issue is written in English. Please use one of the great, free online translation services, such as [DeepL](https://www.deepl.com/translator) to translate from your native language to English if you are not comfortable in English. +- Check whether your issue might be solved by updating to the newest Diffusers version. Before posting your issue, please make sure that `python -c "import diffusers; print(diffusers.__version__)"` is higher or matches the latest Diffusers version. +- Remember that the more effort you put into opening a new issue, the higher the quality of your answer will be and the better the overall quality of the Diffusers issues. + +New issues usually include the following. + +#### 2.1. Reproducible, minimal bug reports + +A bug report should always have a reproducible code snippet and be as minimal and concise as possible. +This means in more detail: +- Narrow the bug down as much as you can, **do not just dump your whole code file**. +- Format your code. +- Do not include any external libraries except for Diffusers depending on them. +- **Always** provide all necessary information about your environment; for this, you can run: `diffusers-cli env` in your shell and copy-paste the displayed information to the issue. +- Explain the issue. If the reader doesn't know what the issue is and why it is an issue, (s)he cannot solve it. +- **Always** make sure the reader can reproduce your issue with as little effort as possible. If your code snippet cannot be run because of missing libraries or undefined variables, the reader cannot help you. Make sure your reproducible code snippet is as minimal as possible and can be copy-pasted into a simple Python shell. +- If in order to reproduce your issue a model and/or dataset is required, make sure the reader has access to that model or dataset. You can always upload your model or dataset to the [Hub](https://huggingface.co) to make it easily downloadable. Try to keep your model and dataset as small as possible, to make the reproduction of your issue as effortless as possible. + +For more information, please have a look through the [How to write a good issue](#how-to-write-a-good-issue) section. + +You can open a bug report [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=bug&projects=&template=bug-report.yml). + +#### 2.2. Feature requests + +A world-class feature request addresses the following points: + +1. Motivation first: +* Is it related to a problem/frustration with the library? If so, please explain +why. Providing a code snippet that demonstrates the problem is best. +* Is it related to something you would need for a project? We'd love to hear +about it! +* Is it something you worked on and think could benefit the community? +Awesome! Tell us what problem it solved for you. +2. Write a *full paragraph* describing the feature; +3. Provide a **code snippet** that demonstrates its future use; +4. In case this is related to a paper, please attach a link; +5. Attach any additional information (drawings, screenshots, etc.) you think may help. + +You can open a feature request [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feature_request.md&title=). + +#### 2.3 Feedback + +Feedback about the library design and why it is good or not good helps the core maintainers immensely to build a user-friendly library. To understand the philosophy behind the current design philosophy, please have a look [here](https://huggingface.co/docs/diffusers/conceptual/philosophy). If you feel like a certain design choice does not fit with the current design philosophy, please explain why and how it should be changed. If a certain design choice follows the design philosophy too much, hence restricting use cases, explain why and how it should be changed. +If a certain design choice is very useful for you, please also leave a note as this is great feedback for future design decisions. + +You can open an issue about feedback [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feedback.md&title=). + +#### 2.4 Technical questions + +Technical questions are mainly about why certain code of the library was written in a certain way, or what a certain part of the code does. Please make sure to link to the code in question and please provide details on +why this part of the code is difficult to understand. + +You can open an issue about a technical question [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=bug&template=bug-report.yml). + +#### 2.5 Proposal to add a new model, scheduler, or pipeline + +If the diffusion model community released a new model, pipeline, or scheduler that you would like to see in the Diffusers library, please provide the following information: + +* Short description of the diffusion pipeline, model, or scheduler and link to the paper or public release. +* Link to any of its open-source implementation(s). +* Link to the model weights if they are available. + +If you are willing to contribute to the model yourself, let us know so we can best guide you. Also, don't forget +to tag the original author of the component (model, scheduler, pipeline, etc.) by GitHub handle if you can find it. + +You can open a request for a model/pipeline/scheduler [here](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=New+model%2Fpipeline%2Fscheduler&template=new-model-addition.yml). + +### 3. Answering issues on the GitHub issues tab + +Answering issues on GitHub might require some technical knowledge of Diffusers, but we encourage everybody to give it a try even if you are not 100% certain that your answer is correct. +Some tips to give a high-quality answer to an issue: +- Be as concise and minimal as possible. +- Stay on topic. An answer to the issue should concern the issue and only the issue. +- Provide links to code, papers, or other sources that prove or encourage your point. +- Answer in code. If a simple code snippet is the answer to the issue or shows how the issue can be solved, please provide a fully reproducible code snippet. + +Also, many issues tend to be simply off-topic, duplicates of other issues, or irrelevant. It is of great +help to the maintainers if you can answer such issues, encouraging the author of the issue to be +more precise, provide the link to a duplicated issue or redirect them to [the forum](https://discuss.huggingface.co/c/discussion-related-to-httpsgithubcomhuggingfacediffusers/63) or [Discord](https://discord.gg/G7tWnz98XR). + +If you have verified that the issued bug report is correct and requires a correction in the source code, +please have a look at the next sections. + +For all of the following contributions, you will need to open a PR. It is explained in detail how to do so in the [Opening a pull request](#how-to-open-a-pr) section. + +### 4. Fixing a "Good first issue" + +*Good first issues* are marked by the [Good first issue](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22) label. Usually, the issue already +explains how a potential solution should look so that it is easier to fix. +If the issue hasn't been closed and you would like to try to fix this issue, you can just leave a message "I would like to try this issue.". There are usually three scenarios: +- a.) The issue description already proposes a fix. In this case and if the solution makes sense to you, you can open a PR or draft PR to fix it. +- b.) The issue description does not propose a fix. In this case, you can ask what a proposed fix could look like and someone from the Diffusers team should answer shortly. If you have a good idea of how to fix it, feel free to directly open a PR. +- c.) There is already an open PR to fix the issue, but the issue hasn't been closed yet. If the PR has gone stale, you can simply open a new PR and link to the stale PR. PRs often go stale if the original contributor who wanted to fix the issue suddenly cannot find the time anymore to proceed. This often happens in open-source and is very normal. In this case, the community will be very happy if you give it a new try and leverage the knowledge of the existing PR. If there is already a PR and it is active, you can help the author by giving suggestions, reviewing the PR or even asking whether you can contribute to the PR. + + +### 5. Contribute to the documentation + +A good library **always** has good documentation! The official documentation is often one of the first points of contact for new users of the library, and therefore contributing to the documentation is a **highly +valuable contribution**. + +Contributing to the library can have many forms: + +- Correcting spelling or grammatical errors. +- Correct incorrect formatting of the docstring. If you see that the official documentation is weirdly displayed or a link is broken, we would be very happy if you take some time to correct it. +- Correct the shape or dimensions of a docstring input or output tensor. +- Clarify documentation that is hard to understand or incorrect. +- Update outdated code examples. +- Translating the documentation to another language. + +Anything displayed on [the official Diffusers doc page](https://huggingface.co/docs/diffusers/index) is part of the official documentation and can be corrected, adjusted in the respective [documentation source](https://github.com/huggingface/diffusers/tree/main/docs/source). + +Please have a look at [this page](https://github.com/huggingface/diffusers/tree/main/docs) on how to verify changes made to the documentation locally. + +### 6. Contribute a community pipeline + +> [!TIP] +> Read the [Community pipelines](../using-diffusers/custom_pipeline_overview#community-pipelines) guide to learn more about the difference between a GitHub and Hugging Face Hub community pipeline. If you're interested in why we have community pipelines, take a look at GitHub Issue [#841](https://github.com/huggingface/diffusers/issues/841) (basically, we can't maintain all the possible ways diffusion models can be used for inference but we also don't want to prevent the community from building them). + +Contributing a community pipeline is a great way to share your creativity and work with the community. It lets you build on top of the [`DiffusionPipeline`] so that anyone can load and use it by setting the `custom_pipeline` parameter. This section will walk you through how to create a simple pipeline where the UNet only does a single forward pass and calls the scheduler once (a "one-step" pipeline). + +1. Create a one_step_unet.py file for your community pipeline. This file can contain whatever package you want to use as long as it's installed by the user. Make sure you only have one pipeline class that inherits from [`DiffusionPipeline`] to load model weights and the scheduler configuration from the Hub. Add a UNet and scheduler to the `__init__` function. + + You should also add the `register_modules` function to ensure your pipeline and its components can be saved with [`~DiffusionPipeline.save_pretrained`]. + +```py +from diffusers import DiffusionPipeline +import torch + +class UnetSchedulerOneForwardPipeline(DiffusionPipeline): + def __init__(self, unet, scheduler): + super().__init__() + + self.register_modules(unet=unet, scheduler=scheduler) +``` + +1. In the forward pass (which we recommend defining as `__call__`), you can add any feature you'd like. For the "one-step" pipeline, create a random image and call the UNet and scheduler once by setting `timestep=1`. + +```py + from diffusers import DiffusionPipeline + import torch + + class UnetSchedulerOneForwardPipeline(DiffusionPipeline): + def __init__(self, unet, scheduler): + super().__init__() + + self.register_modules(unet=unet, scheduler=scheduler) + + def __call__(self): + image = torch.randn( + (1, self.unet.config.in_channels, self.unet.config.sample_size, self.unet.config.sample_size), + ) + timestep = 1 + + model_output = self.unet(image, timestep).sample + scheduler_output = self.scheduler.step(model_output, timestep, image).prev_sample + + return scheduler_output +``` + +Now you can run the pipeline by passing a UNet and scheduler to it or load pretrained weights if the pipeline structure is identical. + +```py +from diffusers import DDPMScheduler, UNet2DModel + +scheduler = DDPMScheduler() +unet = UNet2DModel() + +pipeline = UnetSchedulerOneForwardPipeline(unet=unet, scheduler=scheduler) +output = pipeline() +# load pretrained weights +pipeline = UnetSchedulerOneForwardPipeline.from_pretrained("google/ddpm-cifar10-32", use_safetensors=True) +output = pipeline() +``` + +You can either share your pipeline as a GitHub community pipeline or Hub community pipeline. + + + + +Share your GitHub pipeline by opening a pull request on the Diffusers [repository](https://github.com/huggingface/diffusers) and add the one_step_unet.py file to the [examples/community](https://github.com/huggingface/diffusers/tree/main/examples/community) subfolder. + + + + +Share your Hub pipeline by creating a model repository on the Hub and uploading the one_step_unet.py file to it. + + + + +### 7. Contribute to training examples + +Diffusers examples are a collection of training scripts that reside in [examples](https://github.com/huggingface/diffusers/tree/main/examples). + +We support two types of training examples: + +- Official training examples +- Research training examples + +Research training examples are located in [examples/research_projects](https://github.com/huggingface/diffusers/tree/main/examples/research_projects) whereas official training examples include all folders under [examples](https://github.com/huggingface/diffusers/tree/main/examples) except the `research_projects` and `community` folders. +The official training examples are maintained by the Diffusers' core maintainers whereas the research training examples are maintained by the community. +This is because of the same reasons put forward in [6. Contribute a community pipeline](#6-contribute-a-community-pipeline) for official pipelines vs. community pipelines: It is not feasible for the core maintainers to maintain all possible training methods for diffusion models. +If the Diffusers core maintainers and the community consider a certain training paradigm to be too experimental or not popular enough, the corresponding training code should be put in the `research_projects` folder and maintained by the author. + +Both official training and research examples consist of a directory that contains one or more training scripts, a `requirements.txt` file, and a `README.md` file. In order for the user to make use of the +training examples, it is required to clone the repository: + +```bash +git clone https://github.com/huggingface/diffusers +``` + +as well as to install all additional dependencies required for training: + +```bash +cd diffusers +pip install -r examples//requirements.txt +``` + +Therefore when adding an example, the `requirements.txt` file shall define all pip dependencies required for your training example so that once all those are installed, the user can run the example's training script. See, for example, the [DreamBooth `requirements.txt` file](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/requirements.txt). + +Training examples of the Diffusers library should adhere to the following philosophy: +- All the code necessary to run the examples should be found in a single Python file. +- One should be able to run the example from the command line with `python .py --args`. +- Examples should be kept simple and serve as **an example** on how to use Diffusers for training. The purpose of example scripts is **not** to create state-of-the-art diffusion models, but rather to reproduce known training schemes without adding too much custom logic. As a byproduct of this point, our examples also strive to serve as good educational materials. + +To contribute an example, it is highly recommended to look at already existing examples such as [dreambooth](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/train_dreambooth.py) to get an idea of how they should look like. +We strongly advise contributors to make use of the [Accelerate library](https://github.com/huggingface/accelerate) as it's tightly integrated +with Diffusers. +Once an example script works, please make sure to add a comprehensive `README.md` that states how to use the example exactly. This README should include: +- An example command on how to run the example script as shown [here](https://github.com/huggingface/diffusers/tree/main/examples/dreambooth#running-locally-with-pytorch). +- A link to some training results (logs, models, etc.) that show what the user can expect as shown [here](https://api.wandb.ai/report/patrickvonplaten/xm6cd5q5). +- If you are adding a non-official/research training example, **please don't forget** to add a sentence that you are maintaining this training example which includes your git handle as shown [here](https://github.com/huggingface/diffusers/tree/main/examples/research_projects/intel_opts#diffusers-examples-with-intel-optimizations). + +If you are contributing to the official training examples, please also make sure to add a test to its folder such as [examples/dreambooth/test_dreambooth.py](https://github.com/huggingface/diffusers/blob/main/examples/dreambooth/test_dreambooth.py). This is not necessary for non-official training examples. + +### 8. Fixing a "Good second issue" + +*Good second issues* are marked by the [Good second issue](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22Good+second+issue%22) label. Good second issues are +usually more complicated to solve than [Good first issues](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22good+first+issue%22). +The issue description usually gives less guidance on how to fix the issue and requires +a decent understanding of the library by the interested contributor. +If you are interested in tackling a good second issue, feel free to open a PR to fix it and link the PR to the issue. If you see that a PR has already been opened for this issue but did not get merged, have a look to understand why it wasn't merged and try to open an improved PR. +Good second issues are usually more difficult to get merged compared to good first issues, so don't hesitate to ask for help from the core maintainers. If your PR is almost finished the core maintainers can also jump into your PR and commit to it in order to get it merged. + +### 9. Adding pipelines, models, schedulers + +Pipelines, models, and schedulers are the most important pieces of the Diffusers library. +They provide easy access to state-of-the-art diffusion technologies and thus allow the community to +build powerful generative AI applications. + +By adding a new model, pipeline, or scheduler you might enable a new powerful use case for any of the user interfaces relying on Diffusers which can be of immense value for the whole generative AI ecosystem. + +Diffusers has a couple of open feature requests for all three components - feel free to gloss over them +if you don't know yet what specific component you would like to add: +- [Model or pipeline](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+pipeline%2Fmodel%22) +- [Scheduler](https://github.com/huggingface/diffusers/issues?q=is%3Aopen+is%3Aissue+label%3A%22New+scheduler%22) + +Before adding any of the three components, it is strongly recommended that you give the [Philosophy guide](philosophy) a read to better understand the design of any of the three components. Please be aware that we cannot merge model, scheduler, or pipeline additions that strongly diverge from our design philosophy +as it will lead to API inconsistencies. If you fundamentally disagree with a design choice, please open a [Feedback issue](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feedback.md&title=) instead so that it can be discussed whether a certain design pattern/design choice shall be changed everywhere in the library and whether we shall update our design philosophy. Consistency across the library is very important for us. + +Please make sure to add links to the original codebase/paper to the PR and ideally also ping the original author directly on the PR so that they can follow the progress and potentially help with questions. + +If you are unsure or stuck in the PR, don't hesitate to leave a message to ask for a first review or help. + +#### Copied from mechanism + +A unique and important feature to understand when adding any pipeline, model or scheduler code is the `# Copied from` mechanism. You'll see this all over the Diffusers codebase, and the reason we use it is to keep the codebase easy to understand and maintain. Marking code with the `# Copied from` mechanism forces the marked code to be identical to the code it was copied from. This makes it easy to update and propagate changes across many files whenever you run `make fix-copies`. + +For example, in the code example below, [`~diffusers.pipelines.stable_diffusion.StableDiffusionPipelineOutput`] is the original code and `AltDiffusionPipelineOutput` uses the `# Copied from` mechanism to copy it. The only difference is changing the class prefix from `Stable` to `Alt`. + +```py +# Copied from diffusers.pipelines.stable_diffusion.pipeline_output.StableDiffusionPipelineOutput with Stable->Alt +class AltDiffusionPipelineOutput(BaseOutput): + """ + Output class for Alt Diffusion pipelines. + + Args: + images (`List[PIL.Image.Image]` or `np.ndarray`) + List of denoised PIL images of length `batch_size` or NumPy array of shape `(batch_size, height, width, + num_channels)`. + nsfw_content_detected (`List[bool]`) + List indicating whether the corresponding generated image contains "not-safe-for-work" (nsfw) content or + `None` if safety checking could not be performed. + """ +``` + +To learn more, read this section of the [~Don't~ Repeat Yourself*](https://huggingface.co/blog/transformers-design-philosophy#4-machine-learning-models-are-static) blog post. + +## How to write a good issue + +**The better your issue is written, the higher the chances that it will be quickly resolved.** + +1. Make sure that you've used the correct template for your issue. You can pick between *Bug Report*, *Feature Request*, *Feedback about API Design*, *New model/pipeline/scheduler addition*, *Forum*, or a blank issue. Make sure to pick the correct one when opening [a new issue](https://github.com/huggingface/diffusers/issues/new/choose). +2. **Be precise**: Give your issue a fitting title. Try to formulate your issue description as simple as possible. The more precise you are when submitting an issue, the less time it takes to understand the issue and potentially solve it. Make sure to open an issue for one issue only and not for multiple issues. If you found multiple issues, simply open multiple issues. If your issue is a bug, try to be as precise as possible about what bug it is - you should not just write "Error in diffusers". +3. **Reproducibility**: No reproducible code snippet == no solution. If you encounter a bug, maintainers **have to be able to reproduce** it. Make sure that you include a code snippet that can be copy-pasted into a Python interpreter to reproduce the issue. Make sure that your code snippet works, *i.e.* that there are no missing imports or missing links to images, ... Your issue should contain an error message **and** a code snippet that can be copy-pasted without any changes to reproduce the exact same error message. If your issue is using local model weights or local data that cannot be accessed by the reader, the issue cannot be solved. If you cannot share your data or model, try to make a dummy model or dummy data. +4. **Minimalistic**: Try to help the reader as much as you can to understand the issue as quickly as possible by staying as concise as possible. Remove all code / all information that is irrelevant to the issue. If you have found a bug, try to create the easiest code example you can to demonstrate your issue, do not just dump your whole workflow into the issue as soon as you have found a bug. E.g., if you train a model and get an error at some point during the training, you should first try to understand what part of the training code is responsible for the error and try to reproduce it with a couple of lines. Try to use dummy data instead of full datasets. +5. Add links. If you are referring to a certain naming, method, or model make sure to provide a link so that the reader can better understand what you mean. If you are referring to a specific PR or issue, make sure to link it to your issue. Do not assume that the reader knows what you are talking about. The more links you add to your issue the better. +6. Formatting. Make sure to nicely format your issue by formatting code into Python code syntax, and error messages into normal code syntax. See the [official GitHub formatting docs](https://docs.github.com/en/get-started/writing-on-github/getting-started-with-writing-and-formatting-on-github/basic-writing-and-formatting-syntax) for more information. +7. Think of your issue not as a ticket to be solved, but rather as a beautiful entry to a well-written encyclopedia. Every added issue is a contribution to publicly available knowledge. By adding a nicely written issue you not only make it easier for maintainers to solve your issue, but you are helping the whole community to better understand a certain aspect of the library. + +## How to write a good PR + +1. Be a chameleon. Understand existing design patterns and syntax and make sure your code additions flow seamlessly into the existing code base. Pull requests that significantly diverge from existing design patterns or user interfaces will not be merged. +2. Be laser focused. A pull request should solve one problem and one problem only. Make sure to not fall into the trap of "also fixing another problem while we're adding it". It is much more difficult to review pull requests that solve multiple, unrelated problems at once. +3. If helpful, try to add a code snippet that displays an example of how your addition can be used. +4. The title of your pull request should be a summary of its contribution. +5. If your pull request addresses an issue, please mention the issue number in +the pull request description to make sure they are linked (and people +consulting the issue know you are working on it); +6. To indicate a work in progress please prefix the title with `[WIP]`. These +are useful to avoid duplicated work, and to differentiate it from PRs ready +to be merged; +7. Try to formulate and format your text as explained in [How to write a good issue](#how-to-write-a-good-issue). +8. Make sure existing tests pass; +9. Add high-coverage tests. No quality testing = no merge. +- If you are adding new `@slow` tests, make sure they pass using +`RUN_SLOW=1 python -m pytest tests/test_my_new_model.py`. +CircleCI does not run the slow tests, but GitHub Actions does every night! +10. All public methods must have informative docstrings that work nicely with markdown. See [`pipeline_latent_diffusion.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/latent_diffusion/pipeline_latent_diffusion.py) for an example. +11. Due to the rapidly growing repository, it is important to make sure that no files that would significantly weigh down the repository are added. This includes images, videos, and other non-text files. We prefer to leverage a hf.co hosted `dataset` like +[`hf-internal-testing`](https://huggingface.co/hf-internal-testing) or [huggingface/documentation-images](https://huggingface.co/datasets/huggingface/documentation-images) to place these files. +If an external contribution, feel free to add the images to your PR and ask a Hugging Face member to migrate your images +to this dataset. + +## How to open a PR + +Before writing code, we strongly advise you to search through the existing PRs or +issues to make sure that nobody is already working on the same thing. If you are +unsure, it is always a good idea to open an issue to get some feedback. + +You will need basic `git` proficiency to be able to contribute to +🧨 Diffusers. `git` is not the easiest tool to use but it has the greatest +manual. Type `git --help` in a shell and enjoy. If you prefer books, [Pro +Git](https://git-scm.com/book/en/v2) is a very good reference. + +Follow these steps to start contributing ([supported Python versions](https://github.com/huggingface/diffusers/blob/83bc6c94eaeb6f7704a2a428931cf2d9ad973ae9/setup.py#L270)): + +1. Fork the [repository](https://github.com/huggingface/diffusers) by +clicking on the 'Fork' button on the repository's page. This creates a copy of the code +under your GitHub user account. + +2. Clone your fork to your local disk, and add the base repository as a remote: + + ```bash + $ git clone git@github.com:/diffusers.git + $ cd diffusers + $ git remote add upstream https://github.com/huggingface/diffusers.git + ``` + +3. Create a new branch to hold your development changes: + + ```bash + $ git checkout -b a-descriptive-name-for-my-changes + ``` + +**Do not** work on the `main` branch. + +4. Set up a development environment by running the following command in a virtual environment: + + ```bash + $ pip install -e ".[dev]" + ``` + +If you have already cloned the repo, you might need to `git pull` to get the most recent changes in the +library. + +5. Develop the features on your branch. + +As you work on the features, you should make sure that the test suite +passes. You should run the tests impacted by your changes like this: + + ```bash + $ pytest tests/.py + ``` + +Before you run the tests, please make sure you install the dependencies required for testing. You can do so +with this command: + + ```bash + $ pip install -e ".[test]" + ``` + +You can also run the full test suite with the following command, but it takes +a beefy machine to produce a result in a decent amount of time now that +Diffusers has grown a lot. Here is the command for it: + + ```bash + $ make test + ``` + +🧨 Diffusers relies on `black` and `isort` to format its source code +consistently. After you make changes, apply automatic style corrections and code verifications +that can't be automated in one go with: + + ```bash + $ make style + ``` + +🧨 Diffusers also uses `ruff` and a few custom scripts to check for coding mistakes. Quality +control runs in CI, however, you can also run the same checks with: + + ```bash + $ make quality + ``` + +Once you're happy with your changes, add changed files using `git add` and +make a commit with `git commit` to record your changes locally: + + ```bash + $ git add modified_file.py + $ git commit -m "A descriptive message about your changes." + ``` + +It is a good idea to sync your copy of the code with the original +repository regularly. This way you can quickly account for changes: + + ```bash + $ git pull upstream main + ``` + +Push the changes to your account using: + + ```bash + $ git push -u origin a-descriptive-name-for-my-changes + ``` + +6. Once you are satisfied, go to the +webpage of your fork on GitHub. Click on 'Pull request' to send your changes +to the project maintainers for review. + +7. It's OK if maintainers ask you for changes. It happens to core contributors +too! So everyone can see the changes in the Pull request, work in your local +branch and push the changes to your fork. They will automatically appear in +the pull request. + +### Tests + +An extensive test suite is included to test the library behavior and several examples. Library tests can be found in +the [tests folder](https://github.com/huggingface/diffusers/tree/main/tests). + +We like `pytest` and `pytest-xdist` because it's faster. From the root of the +repository, here's how to run tests with `pytest` for the library: + +```bash +$ python -m pytest -n auto --dist=loadfile -s -v ./tests/ +``` + +In fact, that's how `make test` is implemented! + +You can specify a smaller set of tests in order to test only the feature +you're working on. + +By default, slow tests are skipped. Set the `RUN_SLOW` environment variable to +`yes` to run them. This will download many gigabytes of models — make sure you +have enough disk space and a good Internet connection, or a lot of patience! + +```bash +$ RUN_SLOW=yes python -m pytest -n auto --dist=loadfile -s -v ./tests/ +``` + +`unittest` is fully supported, here's how to run tests with it: + +```bash +$ python -m unittest discover -s tests -t . -v +$ python -m unittest discover -s examples -t examples -v +``` + +### Syncing forked main with upstream (HuggingFace) main + +To avoid pinging the upstream repository which adds reference notes to each upstream PR and sends unnecessary notifications to the developers involved in these PRs, +when syncing the main branch of a forked repository, please, follow these steps: +1. When possible, avoid syncing with the upstream using a branch and PR on the forked repository. Instead, merge directly into the forked main. +2. If a PR is absolutely necessary, use the following steps after checking out your branch: +```bash +$ git checkout -b your-branch-for-syncing +$ git pull --squash --no-commit upstream main +$ git commit -m '' +$ git push --set-upstream origin your-branch-for-syncing +``` + +### Style guide + +For documentation strings, 🧨 Diffusers follows the [Google style](https://google.github.io/styleguide/pyguide.html). \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/conceptual/ethical_guidelines.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/conceptual/ethical_guidelines.md new file mode 100644 index 0000000000000000000000000000000000000000..53e243398003f7a7c6d75f1c879153b177f0b258 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/conceptual/ethical_guidelines.md @@ -0,0 +1,63 @@ + + +# 🧨 Diffusers’ Ethical Guidelines + +## Preamble + +[Diffusers](https://huggingface.co/docs/diffusers/index) provides pre-trained diffusion models and serves as a modular toolbox for inference and training. + +Given its real case applications in the world and potential negative impacts on society, we think it is important to provide the project with ethical guidelines to guide the development, users’ contributions, and usage of the Diffusers library. + +The risks associated with using this technology are still being examined, but to name a few: copyrights issues for artists; deep-fake exploitation; sexual content generation in inappropriate contexts; non-consensual impersonation; harmful social biases perpetuating the oppression of marginalized groups. +We will keep tracking risks and adapt the following guidelines based on the community's responsiveness and valuable feedback. + + +## Scope + +The Diffusers community will apply the following ethical guidelines to the project’s development and help coordinate how the community will integrate the contributions, especially concerning sensitive topics related to ethical concerns. + + +## Ethical guidelines + +The following ethical guidelines apply generally, but we will primarily implement them when dealing with ethically sensitive issues while making a technical choice. Furthermore, we commit to adapting those ethical principles over time following emerging harms related to the state of the art of the technology in question. + +- **Transparency**: we are committed to being transparent in managing PRs, explaining our choices to users, and making technical decisions. + +- **Consistency**: we are committed to guaranteeing our users the same level of attention in project management, keeping it technically stable and consistent. + +- **Simplicity**: with a desire to make it easy to use and exploit the Diffusers library, we are committed to keeping the project’s goals lean and coherent. + +- **Accessibility**: the Diffusers project helps lower the entry bar for contributors who can help run it even without technical expertise. Doing so makes research artifacts more accessible to the community. + +- **Reproducibility**: we aim to be transparent about the reproducibility of upstream code, models, and datasets when made available through the Diffusers library. + +- **Responsibility**: as a community and through teamwork, we hold a collective responsibility to our users by anticipating and mitigating this technology's potential risks and dangers. + + +## Examples of implementations: Safety features and Mechanisms + +The team works daily to make the technical and non-technical tools available to deal with the potential ethical and social risks associated with diffusion technology. Moreover, the community's input is invaluable in ensuring these features' implementation and raising awareness with us. + +- [**Community tab**](https://huggingface.co/docs/hub/repositories-pull-requests-discussions): it enables the community to discuss and better collaborate on a project. + +- **Bias exploration and evaluation**: the Hugging Face team provides a [space](https://huggingface.co/spaces/society-ethics/DiffusionBiasExplorer) to demonstrate the biases in Stable Diffusion interactively. In this sense, we support and encourage bias explorers and evaluations. + +- **Encouraging safety in deployment** + + - [**Safe Stable Diffusion**](https://huggingface.co/docs/diffusers/main/en/api/pipelines/stable_diffusion/stable_diffusion_safe): It mitigates the well-known issue that models, like Stable Diffusion, that are trained on unfiltered, web-crawled datasets tend to suffer from inappropriate degeneration. Related paper: [Safe Latent Diffusion: Mitigating Inappropriate Degeneration in Diffusion Models](https://huggingface.co/papers/2211.05105). + + - [**Safety Checker**](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/safety_checker.py): It checks and compares the class probability of a set of hard-coded harmful concepts in the embedding space against an image after it has been generated. The harmful concepts are intentionally hidden to prevent reverse engineering of the checker. + +- **Staged released on the Hub**: in particularly sensitive situations, access to some repositories should be restricted. This staged release is an intermediary step that allows the repository’s authors to have more control over its use. + +- **Licensing**: [OpenRAILs](https://huggingface.co/blog/open_rail), a new type of licensing, allow us to ensure free access while having a set of restrictions that ensure more responsible use. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/conceptual/evaluation.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/conceptual/evaluation.md new file mode 100644 index 0000000000000000000000000000000000000000..9a16e75f6134c655e92a3f6ecca5bfdc0bae7f71 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/conceptual/evaluation.md @@ -0,0 +1,578 @@ + + +# Evaluating Diffusion Models + + + Open In Colab + + +> [!TIP] +> This document has now grown outdated given the emergence of existing evaluation frameworks for diffusion models for image generation. Please check +> out works like [HEIM](https://crfm.stanford.edu/helm/heim/latest/), [T2I-Compbench](https://huggingface.co/papers/2307.06350), +> [GenEval](https://huggingface.co/papers/2310.11513). + +Evaluation of generative models like [Stable Diffusion](https://huggingface.co/docs/diffusers/stable_diffusion) is subjective in nature. But as practitioners and researchers, we often have to make careful choices amongst many different possibilities. So, when working with different generative models (like GANs, Diffusion, etc.), how do we choose one over the other? + +Qualitative evaluation of such models can be error-prone and might incorrectly influence a decision. +However, quantitative metrics don't necessarily correspond to image quality. So, usually, a combination +of both qualitative and quantitative evaluations provides a stronger signal when choosing one model +over the other. + +In this document, we provide a non-exhaustive overview of qualitative and quantitative methods to evaluate Diffusion models. For quantitative methods, we specifically focus on how to implement them alongside `diffusers`. + +The methods shown in this document can also be used to evaluate different [noise schedulers](https://huggingface.co/docs/diffusers/main/en/api/schedulers/overview) keeping the underlying generation model fixed. + +## Scenarios + +We cover Diffusion models with the following pipelines: + +- Text-guided image generation (such as the [`StableDiffusionPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/stable_diffusion/text2img)). +- Text-guided image generation, additionally conditioned on an input image (such as the [`StableDiffusionImg2ImgPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/stable_diffusion/img2img) and [`StableDiffusionInstructPix2PixPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/pix2pix)). +- Class-conditioned image generation models (such as the [`DiTPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/dit)). + +## Qualitative Evaluation + +Qualitative evaluation typically involves human assessment of generated images. Quality is measured across aspects such as compositionality, image-text alignment, and spatial relations. Common prompts provide a degree of uniformity for subjective metrics. +DrawBench and PartiPrompts are prompt datasets used for qualitative benchmarking. DrawBench and PartiPrompts were introduced by [Imagen](https://imagen.research.google/) and [Parti](https://parti.research.google/) respectively. + +From the [official Parti website](https://parti.research.google/): + +> PartiPrompts (P2) is a rich set of over 1600 prompts in English that we release as part of this work. P2 can be used to measure model capabilities across various categories and challenge aspects. + +![parti-prompts](https://huggingface.co/datasets/diffusers/docs-images/resolve/main/evaluation_diffusion_models/parti-prompts.png) + +PartiPrompts has the following columns: + +- Prompt +- Category of the prompt (such as “Abstract”, “World Knowledge”, etc.) +- Challenge reflecting the difficulty (such as “Basic”, “Complex”, “Writing & Symbols”, etc.) + +These benchmarks allow for side-by-side human evaluation of different image generation models. + +For this, the 🧨 Diffusers team has built **Open Parti Prompts**, which is a community-driven qualitative benchmark based on Parti Prompts to compare state-of-the-art open-source diffusion models: +- [Open Parti Prompts Game](https://huggingface.co/spaces/OpenGenAI/open-parti-prompts): For 10 parti prompts, 4 generated images are shown and the user selects the image that suits the prompt best. +- [Open Parti Prompts Leaderboard](https://huggingface.co/spaces/OpenGenAI/parti-prompts-leaderboard): The leaderboard comparing the currently best open-sourced diffusion models to each other. + +To manually compare images, let’s see how we can use `diffusers` on a couple of PartiPrompts. + +Below we show some prompts sampled across different challenges: Basic, Complex, Linguistic Structures, Imagination, and Writing & Symbols. Here we are using PartiPrompts as a [dataset](https://huggingface.co/datasets/nateraw/parti-prompts). + +```python +from datasets import load_dataset + +# prompts = load_dataset("nateraw/parti-prompts", split="train") +# prompts = prompts.shuffle() +# sample_prompts = [prompts[i]["Prompt"] for i in range(5)] + +# Fixing these sample prompts in the interest of reproducibility. +sample_prompts = [ + "a corgi", + "a hot air balloon with a yin-yang symbol, with the moon visible in the daytime sky", + "a car with no windows", + "a cube made of porcupine", + 'The saying "BE EXCELLENT TO EACH OTHER" written on a red brick wall with a graffiti image of a green alien wearing a tuxedo. A yellow fire hydrant is on a sidewalk in the foreground.', +] +``` + +Now we can use these prompts to generate some images using Stable Diffusion ([v1-4 checkpoint](https://huggingface.co/CompVis/stable-diffusion-v1-4)): + +```python +import torch + +seed = 0 +generator = torch.manual_seed(seed) + +images = sd_pipeline(sample_prompts, num_images_per_prompt=1, generator=generator).images +``` + +![parti-prompts-14](https://huggingface.co/datasets/diffusers/docs-images/resolve/main/evaluation_diffusion_models/parti-prompts-14.png) + +We can also set `num_images_per_prompt` accordingly to compare different images for the same prompt. Running the same pipeline but with a different checkpoint ([v1-5](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5)), yields: + +![parti-prompts-15](https://huggingface.co/datasets/diffusers/docs-images/resolve/main/evaluation_diffusion_models/parti-prompts-15.png) + +Once several images are generated from all the prompts using multiple models (under evaluation), these results are presented to human evaluators for scoring. For +more details on the DrawBench and PartiPrompts benchmarks, refer to their respective papers. + + + +It is useful to look at some inference samples while a model is training to measure the +training progress. In our [training scripts](https://github.com/huggingface/diffusers/tree/main/examples/), we support this utility with additional support for +logging to TensorBoard and Weights & Biases. + + + +## Quantitative Evaluation + +In this section, we will walk you through how to evaluate three different diffusion pipelines using: + +- CLIP score +- CLIP directional similarity +- FID + +### Text-guided image generation + +[CLIP score](https://huggingface.co/papers/2104.08718) measures the compatibility of image-caption pairs. Higher CLIP scores imply higher compatibility 🔼. The CLIP score is a quantitative measurement of the qualitative concept "compatibility". Image-caption pair compatibility can also be thought of as the semantic similarity between the image and the caption. CLIP score was found to have high correlation with human judgement. + +Let's first load a [`StableDiffusionPipeline`]: + +```python +from diffusers import StableDiffusionPipeline +import torch + +model_ckpt = "CompVis/stable-diffusion-v1-4" +sd_pipeline = StableDiffusionPipeline.from_pretrained(model_ckpt, torch_dtype=torch.float16).to("cuda") +``` + +Generate some images with multiple prompts: + +```python +prompts = [ + "a photo of an astronaut riding a horse on mars", + "A high tech solarpunk utopia in the Amazon rainforest", + "A pikachu fine dining with a view to the Eiffel Tower", + "A mecha robot in a favela in expressionist style", + "an insect robot preparing a delicious meal", + "A small cabin on top of a snowy mountain in the style of Disney, artstation", +] + +images = sd_pipeline(prompts, num_images_per_prompt=1, output_type="np").images + +print(images.shape) +# (6, 512, 512, 3) +``` + +And then, we calculate the CLIP score. + +```python +from torchmetrics.functional.multimodal import clip_score +from functools import partial + +clip_score_fn = partial(clip_score, model_name_or_path="openai/clip-vit-base-patch16") + +def calculate_clip_score(images, prompts): + images_int = (images * 255).astype("uint8") + clip_score = clip_score_fn(torch.from_numpy(images_int).permute(0, 3, 1, 2), prompts).detach() + return round(float(clip_score), 4) + +sd_clip_score = calculate_clip_score(images, prompts) +print(f"CLIP score: {sd_clip_score}") +# CLIP score: 35.7038 +``` + +In the above example, we generated one image per prompt. If we generated multiple images per prompt, we would have to take the average score from the generated images per prompt. + +Now, if we wanted to compare two checkpoints compatible with the [`StableDiffusionPipeline`] we should pass a generator while calling the pipeline. First, we generate images with a +fixed seed with the [v1-4 Stable Diffusion checkpoint](https://huggingface.co/CompVis/stable-diffusion-v1-4): + +```python +seed = 0 +generator = torch.manual_seed(seed) + +images = sd_pipeline(prompts, num_images_per_prompt=1, generator=generator, output_type="np").images +``` + +Then we load the [v1-5 checkpoint](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) to generate images: + +```python +model_ckpt_1_5 = "stable-diffusion-v1-5/stable-diffusion-v1-5" +sd_pipeline_1_5 = StableDiffusionPipeline.from_pretrained(model_ckpt_1_5, torch_dtype=torch.float16).to("cuda") + +images_1_5 = sd_pipeline_1_5(prompts, num_images_per_prompt=1, generator=generator, output_type="np").images +``` + +And finally, we compare their CLIP scores: + +```python +sd_clip_score_1_4 = calculate_clip_score(images, prompts) +print(f"CLIP Score with v-1-4: {sd_clip_score_1_4}") +# CLIP Score with v-1-4: 34.9102 + +sd_clip_score_1_5 = calculate_clip_score(images_1_5, prompts) +print(f"CLIP Score with v-1-5: {sd_clip_score_1_5}") +# CLIP Score with v-1-5: 36.2137 +``` + +It seems like the [v1-5](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) checkpoint performs better than its predecessor. Note, however, that the number of prompts we used to compute the CLIP scores is quite low. For a more practical evaluation, this number should be way higher, and the prompts should be diverse. + + + +By construction, there are some limitations in this score. The captions in the training dataset +were crawled from the web and extracted from `alt` and similar tags associated an image on the internet. +They are not necessarily representative of what a human being would use to describe an image. Hence we +had to "engineer" some prompts here. + + + +### Image-conditioned text-to-image generation + +In this case, we condition the generation pipeline with an input image as well as a text prompt. Let's take the [`StableDiffusionInstructPix2PixPipeline`], as an example. It takes an edit instruction as an input prompt and an input image to be edited. + +Here is one example: + +![edit-instruction](https://huggingface.co/datasets/diffusers/docs-images/resolve/main/evaluation_diffusion_models/edit-instruction.png) + +One strategy to evaluate such a model is to measure the consistency of the change between the two images (in [CLIP](https://huggingface.co/docs/transformers/model_doc/clip) space) with the change between the two image captions (as shown in [CLIP-Guided Domain Adaptation of Image Generators](https://huggingface.co/papers/2108.00946)). This is referred to as the "**CLIP directional similarity**". + +- Caption 1 corresponds to the input image (image 1) that is to be edited. +- Caption 2 corresponds to the edited image (image 2). It should reflect the edit instruction. + +Following is a pictorial overview: + +![edit-consistency](https://huggingface.co/datasets/diffusers/docs-images/resolve/main/evaluation_diffusion_models/edit-consistency.png) + +We have prepared a mini dataset to implement this metric. Let's first load the dataset. + +```python +from datasets import load_dataset + +dataset = load_dataset("sayakpaul/instructpix2pix-demo", split="train") +dataset.features +``` + +```bash +{'input': Value(dtype='string', id=None), + 'edit': Value(dtype='string', id=None), + 'output': Value(dtype='string', id=None), + 'image': Image(decode=True, id=None)} +``` + +Here we have: + +- `input` is a caption corresponding to the `image`. +- `edit` denotes the edit instruction. +- `output` denotes the modified caption reflecting the `edit` instruction. + +Let's take a look at a sample. + +```python +idx = 0 +print(f"Original caption: {dataset[idx]['input']}") +print(f"Edit instruction: {dataset[idx]['edit']}") +print(f"Modified caption: {dataset[idx]['output']}") +``` + +```bash +Original caption: 2. FAROE ISLANDS: An archipelago of 18 mountainous isles in the North Atlantic Ocean between Norway and Iceland, the Faroe Islands has 'everything you could hope for', according to Big 7 Travel. It boasts 'crystal clear waterfalls, rocky cliffs that seem to jut out of nowhere and velvety green hills' +Edit instruction: make the isles all white marble +Modified caption: 2. WHITE MARBLE ISLANDS: An archipelago of 18 mountainous white marble isles in the North Atlantic Ocean between Norway and Iceland, the White Marble Islands has 'everything you could hope for', according to Big 7 Travel. It boasts 'crystal clear waterfalls, rocky cliffs that seem to jut out of nowhere and velvety green hills' +``` + +And here is the image: + +```python +dataset[idx]["image"] +``` + +![edit-dataset](https://huggingface.co/datasets/diffusers/docs-images/resolve/main/evaluation_diffusion_models/edit-dataset.png) + +We will first edit the images of our dataset with the edit instruction and compute the directional similarity. + +Let's first load the [`StableDiffusionInstructPix2PixPipeline`]: + +```python +from diffusers import StableDiffusionInstructPix2PixPipeline + +instruct_pix2pix_pipeline = StableDiffusionInstructPix2PixPipeline.from_pretrained( + "timbrooks/instruct-pix2pix", torch_dtype=torch.float16 +).to("cuda") +``` + +Now, we perform the edits: + +```python +import numpy as np + + +def edit_image(input_image, instruction): + image = instruct_pix2pix_pipeline( + instruction, + image=input_image, + output_type="np", + generator=generator, + ).images[0] + return image + +input_images = [] +original_captions = [] +modified_captions = [] +edited_images = [] + +for idx in range(len(dataset)): + input_image = dataset[idx]["image"] + edit_instruction = dataset[idx]["edit"] + edited_image = edit_image(input_image, edit_instruction) + + input_images.append(np.array(input_image)) + original_captions.append(dataset[idx]["input"]) + modified_captions.append(dataset[idx]["output"]) + edited_images.append(edited_image) +``` + +To measure the directional similarity, we first load CLIP's image and text encoders: + +```python +from transformers import ( + CLIPTokenizer, + CLIPTextModelWithProjection, + CLIPVisionModelWithProjection, + CLIPImageProcessor, +) + +clip_id = "openai/clip-vit-large-patch14" +tokenizer = CLIPTokenizer.from_pretrained(clip_id) +text_encoder = CLIPTextModelWithProjection.from_pretrained(clip_id).to("cuda") +image_processor = CLIPImageProcessor.from_pretrained(clip_id) +image_encoder = CLIPVisionModelWithProjection.from_pretrained(clip_id).to("cuda") +``` + +Notice that we are using a particular CLIP checkpoint, i.e., `openai/clip-vit-large-patch14`. This is because the Stable Diffusion pre-training was performed with this CLIP variant. For more details, refer to the [documentation](https://huggingface.co/docs/transformers/model_doc/clip). + +Next, we prepare a PyTorch `nn.Module` to compute directional similarity: + +```python +import torch.nn as nn +import torch.nn.functional as F + + +class DirectionalSimilarity(nn.Module): + def __init__(self, tokenizer, text_encoder, image_processor, image_encoder): + super().__init__() + self.tokenizer = tokenizer + self.text_encoder = text_encoder + self.image_processor = image_processor + self.image_encoder = image_encoder + + def preprocess_image(self, image): + image = self.image_processor(image, return_tensors="pt")["pixel_values"] + return {"pixel_values": image.to("cuda")} + + def tokenize_text(self, text): + inputs = self.tokenizer( + text, + max_length=self.tokenizer.model_max_length, + padding="max_length", + truncation=True, + return_tensors="pt", + ) + return {"input_ids": inputs.input_ids.to("cuda")} + + def encode_image(self, image): + preprocessed_image = self.preprocess_image(image) + image_features = self.image_encoder(**preprocessed_image).image_embeds + image_features = image_features / image_features.norm(dim=1, keepdim=True) + return image_features + + def encode_text(self, text): + tokenized_text = self.tokenize_text(text) + text_features = self.text_encoder(**tokenized_text).text_embeds + text_features = text_features / text_features.norm(dim=1, keepdim=True) + return text_features + + def compute_directional_similarity(self, img_feat_one, img_feat_two, text_feat_one, text_feat_two): + sim_direction = F.cosine_similarity(img_feat_two - img_feat_one, text_feat_two - text_feat_one) + return sim_direction + + def forward(self, image_one, image_two, caption_one, caption_two): + img_feat_one = self.encode_image(image_one) + img_feat_two = self.encode_image(image_two) + text_feat_one = self.encode_text(caption_one) + text_feat_two = self.encode_text(caption_two) + directional_similarity = self.compute_directional_similarity( + img_feat_one, img_feat_two, text_feat_one, text_feat_two + ) + return directional_similarity +``` + +Let's put `DirectionalSimilarity` to use now. + +```python +dir_similarity = DirectionalSimilarity(tokenizer, text_encoder, image_processor, image_encoder) +scores = [] + +for i in range(len(input_images)): + original_image = input_images[i] + original_caption = original_captions[i] + edited_image = edited_images[i] + modified_caption = modified_captions[i] + + similarity_score = dir_similarity(original_image, edited_image, original_caption, modified_caption) + scores.append(float(similarity_score.detach().cpu())) + +print(f"CLIP directional similarity: {np.mean(scores)}") +# CLIP directional similarity: 0.0797976553440094 +``` + +Like the CLIP Score, the higher the CLIP directional similarity, the better it is. + +It should be noted that the `StableDiffusionInstructPix2PixPipeline` exposes two arguments, namely, `image_guidance_scale` and `guidance_scale` that let you control the quality of the final edited image. We encourage you to experiment with these two arguments and see the impact of that on the directional similarity. + +We can extend the idea of this metric to measure how similar the original image and edited version are. To do that, we can just do `F.cosine_similarity(img_feat_two, img_feat_one)`. For these kinds of edits, we would still want the primary semantics of the images to be preserved as much as possible, i.e., a high similarity score. + +We can use these metrics for similar pipelines such as the [`StableDiffusionPix2PixZeroPipeline`](https://huggingface.co/docs/diffusers/main/en/api/pipelines/pix2pix_zero#diffusers.StableDiffusionPix2PixZeroPipeline). + + + +Both CLIP score and CLIP direction similarity rely on the CLIP model, which can make the evaluations biased. + + + +***Extending metrics like IS, FID (discussed later), or KID can be difficult*** when the model under evaluation was pre-trained on a large image-captioning dataset (such as the [LAION-5B dataset](https://laion.ai/blog/laion-5b/)). This is because underlying these metrics is an InceptionNet (pre-trained on the ImageNet-1k dataset) used for extracting intermediate image features. The pre-training dataset of Stable Diffusion may have limited overlap with the pre-training dataset of InceptionNet, so it is not a good candidate here for feature extraction. + +***Using the above metrics helps evaluate models that are class-conditioned. For example, [DiT](https://huggingface.co/docs/diffusers/main/en/api/pipelines/dit). It was pre-trained being conditioned on the ImageNet-1k classes.*** + +### Class-conditioned image generation + +Class-conditioned generative models are usually pre-trained on a class-labeled dataset such as [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k). Popular metrics for evaluating these models include Fréchet Inception Distance (FID), Kernel Inception Distance (KID), and Inception Score (IS). In this document, we focus on FID ([Heusel et al.](https://huggingface.co/papers/1706.08500)). We show how to compute it with the [`DiTPipeline`](https://huggingface.co/docs/diffusers/api/pipelines/dit), which uses the [DiT model](https://huggingface.co/papers/2212.09748) under the hood. + +FID aims to measure how similar are two datasets of images. As per [this resource](https://mmgeneration.readthedocs.io/en/latest/quick_run.html#fid): + +> Fréchet Inception Distance is a measure of similarity between two datasets of images. It was shown to correlate well with the human judgment of visual quality and is most often used to evaluate the quality of samples of Generative Adversarial Networks. FID is calculated by computing the Fréchet distance between two Gaussians fitted to feature representations of the Inception network. + +These two datasets are essentially the dataset of real images and the dataset of fake images (generated images in our case). FID is usually calculated with two large datasets. However, for this document, we will work with two mini datasets. + +Let's first download a few images from the ImageNet-1k training set: + +```python +from zipfile import ZipFile +import requests + + +def download(url, local_filepath): + r = requests.get(url) + with open(local_filepath, "wb") as f: + f.write(r.content) + return local_filepath + +dummy_dataset_url = "https://hf.co/datasets/sayakpaul/sample-datasets/resolve/main/sample-imagenet-images.zip" +local_filepath = download(dummy_dataset_url, dummy_dataset_url.split("/")[-1]) + +with ZipFile(local_filepath, "r") as zipper: + zipper.extractall(".") +``` + +```python +from PIL import Image +import os +import numpy as np + +dataset_path = "sample-imagenet-images" +image_paths = sorted([os.path.join(dataset_path, x) for x in os.listdir(dataset_path)]) + +real_images = [np.array(Image.open(path).convert("RGB")) for path in image_paths] +``` + +These are 10 images from the following ImageNet-1k classes: "cassette_player", "chain_saw" (x2), "church", "gas_pump" (x3), "parachute" (x2), and "tench". + +
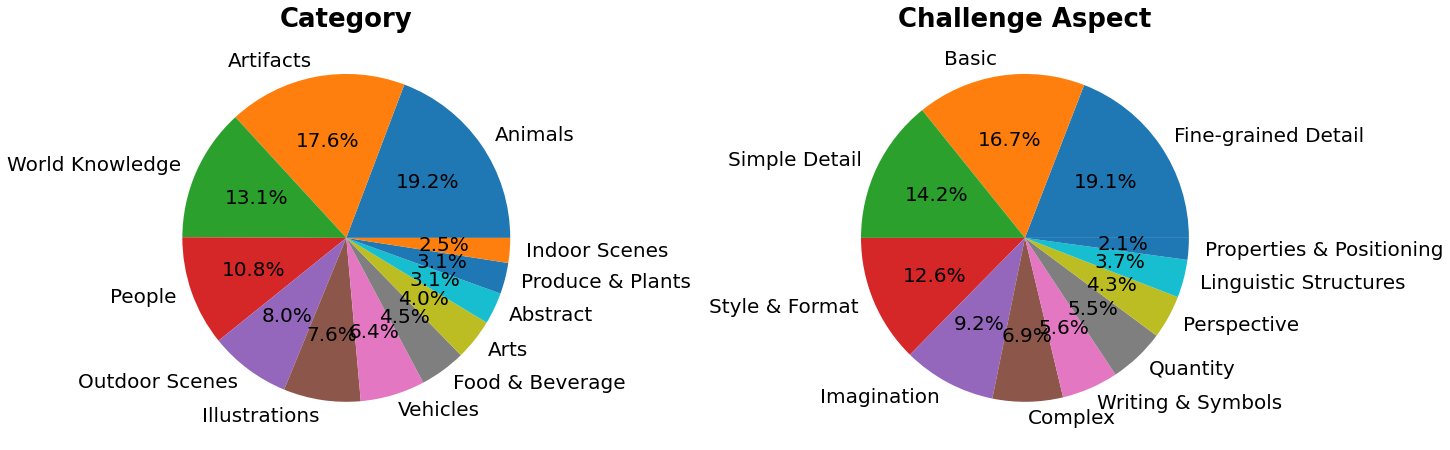
+ real-images
+ Real images. +

+ +Now that the images are loaded, let's apply some lightweight pre-processing on them to use them for FID calculation. + +```python +from torchvision.transforms import functional as F +import torch + + +def preprocess_image(image): + image = torch.tensor(image).unsqueeze(0) + image = image.permute(0, 3, 1, 2) / 255.0 + return F.center_crop(image, (256, 256)) + +real_images = torch.cat([preprocess_image(image) for image in real_images]) +print(real_images.shape) +# torch.Size([10, 3, 256, 256]) +``` + +We now load the [`DiTPipeline`](https://huggingface.co/docs/diffusers/api/pipelines/dit) to generate images conditioned on the above-mentioned classes. + +```python +from diffusers import DiTPipeline, DPMSolverMultistepScheduler + +dit_pipeline = DiTPipeline.from_pretrained("facebook/DiT-XL-2-256", torch_dtype=torch.float16) +dit_pipeline.scheduler = DPMSolverMultistepScheduler.from_config(dit_pipeline.scheduler.config) +dit_pipeline = dit_pipeline.to("cuda") + +seed = 0 +generator = torch.manual_seed(seed) + + +words = [ + "cassette player", + "chainsaw", + "chainsaw", + "church", + "gas pump", + "gas pump", + "gas pump", + "parachute", + "parachute", + "tench", +] + +class_ids = dit_pipeline.get_label_ids(words) +output = dit_pipeline(class_labels=class_ids, generator=generator, output_type="np") + +fake_images = output.images +fake_images = torch.tensor(fake_images) +fake_images = fake_images.permute(0, 3, 1, 2) +print(fake_images.shape) +# torch.Size([10, 3, 256, 256]) +``` + +Now, we can compute the FID using [`torchmetrics`](https://torchmetrics.readthedocs.io/). + +```python +from torchmetrics.image.fid import FrechetInceptionDistance + +fid = FrechetInceptionDistance(normalize=True) +fid.update(real_images, real=True) +fid.update(fake_images, real=False) + +print(f"FID: {float(fid.compute())}") +# FID: 177.7147216796875 +``` + +The lower the FID, the better it is. Several things can influence FID here: + +- Number of images (both real and fake) +- Randomness induced in the diffusion process +- Number of inference steps in the diffusion process +- The scheduler being used in the diffusion process + +For the last two points, it is, therefore, a good practice to run the evaluation across different seeds and inference steps, and then report an average result. + + + +FID results tend to be fragile as they depend on a lot of factors: + +* The specific Inception model used during computation. +* The implementation accuracy of the computation. +* The image format (not the same if we start from PNGs vs JPGs). + +Keeping that in mind, FID is often most useful when comparing similar runs, but it is +hard to reproduce paper results unless the authors carefully disclose the FID +measurement code. + +These points apply to other related metrics too, such as KID and IS. + + + +As a final step, let's visually inspect the `fake_images`. + +

+ fake-images
+ Fake images. +

diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/conceptual/philosophy.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/conceptual/philosophy.md new file mode 100644 index 0000000000000000000000000000000000000000..7a351239982b778530635f2fdf4ca69e79a1c259 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/conceptual/philosophy.md @@ -0,0 +1,110 @@ + + +# Philosophy + +🧨 Diffusers provides **state-of-the-art** pretrained diffusion models across multiple modalities. +Its purpose is to serve as a **modular toolbox** for both inference and training. + +We aim at building a library that stands the test of time and therefore take API design very seriously. + +In a nutshell, Diffusers is built to be a natural extension of PyTorch. Therefore, most of our design choices are based on [PyTorch's Design Principles](https://pytorch.org/docs/stable/community/design.html#pytorch-design-philosophy). Let's go over the most important ones: + +## Usability over Performance + +- While Diffusers has many built-in performance-enhancing features (see [Memory and Speed](https://huggingface.co/docs/diffusers/optimization/fp16)), models are always loaded with the highest precision and lowest optimization. Therefore, by default diffusion pipelines are always instantiated on CPU with float32 precision if not otherwise defined by the user. This ensures usability across different platforms and accelerators and means that no complex installations are required to run the library. +- Diffusers aims to be a **light-weight** package and therefore has very few required dependencies, but many soft dependencies that can improve performance (such as `accelerate`, `safetensors`, `onnx`, etc...). We strive to keep the library as lightweight as possible so that it can be added without much concern as a dependency on other packages. +- Diffusers prefers simple, self-explainable code over condensed, magic code. This means that short-hand code syntaxes such as lambda functions, and advanced PyTorch operators are often not desired. + +## Simple over easy + +As PyTorch states, **explicit is better than implicit** and **simple is better than complex**. This design philosophy is reflected in multiple parts of the library: +- We follow PyTorch's API with methods like [`DiffusionPipeline.to`](https://huggingface.co/docs/diffusers/main/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.to) to let the user handle device management. +- Raising concise error messages is preferred to silently correct erroneous input. Diffusers aims at teaching the user, rather than making the library as easy to use as possible. +- Complex model vs. scheduler logic is exposed instead of magically handled inside. Schedulers/Samplers are separated from diffusion models with minimal dependencies on each other. This forces the user to write the unrolled denoising loop. However, the separation allows for easier debugging and gives the user more control over adapting the denoising process or switching out diffusion models or schedulers. +- Separately trained components of the diffusion pipeline, *e.g.* the text encoder, the unet, and the variational autoencoder, each have their own model class. This forces the user to handle the interaction between the different model components, and the serialization format separates the model components into different files. However, this allows for easier debugging and customization. DreamBooth or Textual Inversion training +is very simple thanks to Diffusers' ability to separate single components of the diffusion pipeline. + +## Tweakable, contributor-friendly over abstraction + +For large parts of the library, Diffusers adopts an important design principle of the [Transformers library](https://github.com/huggingface/transformers), which is to prefer copy-pasted code over hasty abstractions. This design principle is very opinionated and stands in stark contrast to popular design principles such as [Don't repeat yourself (DRY)](https://en.wikipedia.org/wiki/Don%27t_repeat_yourself). +In short, just like Transformers does for modeling files, Diffusers prefers to keep an extremely low level of abstraction and very self-contained code for pipelines and schedulers. +Functions, long code blocks, and even classes can be copied across multiple files which at first can look like a bad, sloppy design choice that makes the library unmaintainable. +**However**, this design has proven to be extremely successful for Transformers and makes a lot of sense for community-driven, open-source machine learning libraries because: +- Machine Learning is an extremely fast-moving field in which paradigms, model architectures, and algorithms are changing rapidly, which therefore makes it very difficult to define long-lasting code abstractions. +- Machine Learning practitioners like to be able to quickly tweak existing code for ideation and research and therefore prefer self-contained code over one that contains many abstractions. +- Open-source libraries rely on community contributions and therefore must build a library that is easy to contribute to. The more abstract the code, the more dependencies, the harder to read, and the harder to contribute to. Contributors simply stop contributing to very abstract libraries out of fear of breaking vital functionality. If contributing to a library cannot break other fundamental code, not only is it more inviting for potential new contributors, but it is also easier to review and contribute to multiple parts in parallel. + +At Hugging Face, we call this design the **single-file policy** which means that almost all of the code of a certain class should be written in a single, self-contained file. To read more about the philosophy, you can have a look +at [this blog post](https://huggingface.co/blog/transformers-design-philosophy). + +In Diffusers, we follow this philosophy for both pipelines and schedulers, but only partly for diffusion models. The reason we don't follow this design fully for diffusion models is because almost all diffusion pipelines, such +as [DDPM](https://huggingface.co/docs/diffusers/api/pipelines/ddpm), [Stable Diffusion](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion/overview#stable-diffusion-pipelines), [unCLIP (DALL·E 2)](https://huggingface.co/docs/diffusers/api/pipelines/unclip) and [Imagen](https://imagen.research.google/) all rely on the same diffusion model, the [UNet](https://huggingface.co/docs/diffusers/api/models/unet2d-cond). + +Great, now you should have generally understood why 🧨 Diffusers is designed the way it is 🤗. +We try to apply these design principles consistently across the library. Nevertheless, there are some minor exceptions to the philosophy or some unlucky design choices. If you have feedback regarding the design, we would ❤️ to hear it [directly on GitHub](https://github.com/huggingface/diffusers/issues/new?assignees=&labels=&template=feedback.md&title=). + +## Design Philosophy in Details + +Now, let's look a bit into the nitty-gritty details of the design philosophy. Diffusers essentially consists of three major classes: [pipelines](https://github.com/huggingface/diffusers/tree/main/src/diffusers/pipelines), [models](https://github.com/huggingface/diffusers/tree/main/src/diffusers/models), and [schedulers](https://github.com/huggingface/diffusers/tree/main/src/diffusers/schedulers). +Let's walk through more in-detail design decisions for each class. + +### Pipelines + +Pipelines are designed to be easy to use (therefore do not follow [*Simple over easy*](#simple-over-easy) 100%), are not feature complete, and should loosely be seen as examples of how to use [models](#models) and [schedulers](#schedulers) for inference. + +The following design principles are followed: +- Pipelines follow the single-file policy. All pipelines can be found in individual directories under src/diffusers/pipelines. One pipeline folder corresponds to one diffusion paper/project/release. Multiple pipeline files can be gathered in one pipeline folder, as it’s done for [`src/diffusers/pipelines/stable-diffusion`](https://github.com/huggingface/diffusers/tree/main/src/diffusers/pipelines/stable_diffusion). If pipelines share similar functionality, one can make use of the [# Copied from mechanism](https://github.com/huggingface/diffusers/blob/125d783076e5bd9785beb05367a2d2566843a271/src/diffusers/pipelines/stable_diffusion/pipeline_stable_diffusion_img2img.py#L251). +- Pipelines all inherit from [`DiffusionPipeline`]. +- Every pipeline consists of different model and scheduler components, that are documented in the [`model_index.json` file](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5/blob/main/model_index.json), are accessible under the same name as attributes of the pipeline and can be shared between pipelines with [`DiffusionPipeline.components`](https://huggingface.co/docs/diffusers/main/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.components) function. +- Every pipeline should be loadable via the [`DiffusionPipeline.from_pretrained`](https://huggingface.co/docs/diffusers/main/en/api/diffusion_pipeline#diffusers.DiffusionPipeline.from_pretrained) function. +- Pipelines should be used **only** for inference. +- Pipelines should be very readable, self-explanatory, and easy to tweak. +- Pipelines should be designed to build on top of each other and be easy to integrate into higher-level APIs. +- Pipelines are **not** intended to be feature-complete user interfaces. For feature-complete user interfaces one should rather have a look at [InvokeAI](https://github.com/invoke-ai/InvokeAI), [Diffuzers](https://github.com/abhishekkrthakur/diffuzers), and [lama-cleaner](https://github.com/Sanster/lama-cleaner). +- Every pipeline should have one and only one way to run it via a `__call__` method. The naming of the `__call__` arguments should be shared across all pipelines. +- Pipelines should be named after the task they are intended to solve. +- In almost all cases, novel diffusion pipelines shall be implemented in a new pipeline folder/file. + +### Models + +Models are designed as configurable toolboxes that are natural extensions of [PyTorch's Module class](https://pytorch.org/docs/stable/generated/torch.nn.Module.html). They only partly follow the **single-file policy**. + +The following design principles are followed: +- Models correspond to **a type of model architecture**. *E.g.* the [`UNet2DConditionModel`] class is used for all UNet variations that expect 2D image inputs and are conditioned on some context. +- All models can be found in [`src/diffusers/models`](https://github.com/huggingface/diffusers/tree/main/src/diffusers/models) and every model architecture shall be defined in its file, e.g. [`unets/unet_2d_condition.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/unets/unet_2d_condition.py), [`transformers/transformer_2d.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/transformers/transformer_2d.py), etc... +- Models **do not** follow the single-file policy and should make use of smaller model building blocks, such as [`attention.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention.py), [`resnet.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/resnet.py), [`embeddings.py`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/embeddings.py), etc... **Note**: This is in stark contrast to Transformers' modeling files and shows that models do not really follow the single-file policy. +- Models intend to expose complexity, just like PyTorch's `Module` class, and give clear error messages. +- Models all inherit from `ModelMixin` and `ConfigMixin`. +- Models can be optimized for performance when it doesn’t demand major code changes, keeps backward compatibility, and gives significant memory or compute gain. +- Models should by default have the highest precision and lowest performance setting. +- To integrate new model checkpoints whose general architecture can be classified as an architecture that already exists in Diffusers, the existing model architecture shall be adapted to make it work with the new checkpoint. One should only create a new file if the model architecture is fundamentally different. +- Models should be designed to be easily extendable to future changes. This can be achieved by limiting public function arguments, configuration arguments, and "foreseeing" future changes, *e.g.* it is usually better to add `string` "...type" arguments that can easily be extended to new future types instead of boolean `is_..._type` arguments. Only the minimum amount of changes shall be made to existing architectures to make a new model checkpoint work. +- The model design is a difficult trade-off between keeping code readable and concise and supporting many model checkpoints. For most parts of the modeling code, classes shall be adapted for new model checkpoints, while there are some exceptions where it is preferred to add new classes to make sure the code is kept concise and +readable long-term, such as [UNet blocks](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/unets/unet_2d_blocks.py) and [Attention processors](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention_processor.py). + +### Schedulers + +Schedulers are responsible to guide the denoising process for inference as well as to define a noise schedule for training. They are designed as individual classes with loadable configuration files and strongly follow the **single-file policy**. + +The following design principles are followed: +- All schedulers are found in [`src/diffusers/schedulers`](https://github.com/huggingface/diffusers/tree/main/src/diffusers/schedulers). +- Schedulers are **not** allowed to import from large utils files and shall be kept very self-contained. +- One scheduler Python file corresponds to one scheduler algorithm (as might be defined in a paper). +- If schedulers share similar functionalities, we can make use of the `# Copied from` mechanism. +- Schedulers all inherit from `SchedulerMixin` and `ConfigMixin`. +- Schedulers can be easily swapped out with the [`ConfigMixin.from_config`](https://huggingface.co/docs/diffusers/main/en/api/configuration#diffusers.ConfigMixin.from_config) method as explained in detail [here](../using-diffusers/schedulers). +- Every scheduler has to have a `set_num_inference_steps`, and a `step` function. `set_num_inference_steps(...)` has to be called before every denoising process, *i.e.* before `step(...)` is called. +- Every scheduler exposes the timesteps to be "looped over" via a `timesteps` attribute, which is an array of timesteps the model will be called upon. +- The `step(...)` function takes a predicted model output and the "current" sample (x_t) and returns the "previous", slightly more denoised sample (x_t-1). +- Given the complexity of diffusion schedulers, the `step` function does not expose all the complexity and can be a bit of a "black box". +- In almost all cases, novel schedulers shall be implemented in a new scheduling file. \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/hybrid_inference/api_reference.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/hybrid_inference/api_reference.md new file mode 100644 index 0000000000000000000000000000000000000000..865aaba5ebb6be99ebe115ed90efeff52d61cce1 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/hybrid_inference/api_reference.md @@ -0,0 +1,9 @@ +# Hybrid Inference API Reference + +## Remote Decode + +[[autodoc]] utils.remote_utils.remote_decode + +## Remote Encode + +[[autodoc]] utils.remote_utils.remote_encode diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/hybrid_inference/overview.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/hybrid_inference/overview.md new file mode 100644 index 0000000000000000000000000000000000000000..b44393c77cbd07c7d09c7a5af500a0cabb405894 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/hybrid_inference/overview.md @@ -0,0 +1,60 @@ + + +# Hybrid Inference + +**Empowering local AI builders with Hybrid Inference** + + +> [!TIP] +> Hybrid Inference is an [experimental feature](https://huggingface.co/blog/remote_vae). +> Feedback can be provided [here](https://github.com/huggingface/diffusers/issues/new?template=remote-vae-pilot-feedback.yml). + + + +## Why use Hybrid Inference? + +Hybrid Inference offers a fast and simple way to offload local generation requirements. + +- 🚀 **Reduced Requirements:** Access powerful models without expensive hardware. +- 💎 **Without Compromise:** Achieve the highest quality without sacrificing performance. +- 💰 **Cost Effective:** It's free! 🤑 +- 🎯 **Diverse Use Cases:** Fully compatible with Diffusers 🧨 and the wider community. +- 🔧 **Developer-Friendly:** Simple requests, fast responses. + +--- + +## Available Models + +* **VAE Decode 🖼️:** Quickly decode latent representations into high-quality images without compromising performance or workflow speed. +* **VAE Encode 🔢:** Efficiently encode images into latent representations for generation and training. +* **Text Encoders 📃 (coming soon):** Compute text embeddings for your prompts quickly and accurately, ensuring a smooth and high-quality workflow. + +--- + +## Integrations + +* **[SD.Next](https://github.com/vladmandic/sdnext):** All-in-one UI with direct supports Hybrid Inference. +* **[ComfyUI-HFRemoteVae](https://github.com/kijai/ComfyUI-HFRemoteVae):** ComfyUI node for Hybrid Inference. + +## Changelog + +- March 10 2025: Added VAE encode +- March 2 2025: Initial release with VAE decoding + +## Contents + +The documentation is organized into three sections: + +* **VAE Decode** Learn the basics of how to use VAE Decode with Hybrid Inference. +* **VAE Encode** Learn the basics of how to use VAE Encode with Hybrid Inference. +* **API Reference** Dive into task-specific settings and parameters. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/hybrid_inference/vae_decode.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/hybrid_inference/vae_decode.md new file mode 100644 index 0000000000000000000000000000000000000000..1457090550c724b223ff9470f224f121a3bad74e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/hybrid_inference/vae_decode.md @@ -0,0 +1,345 @@ +# Getting Started: VAE Decode with Hybrid Inference + +VAE decode is an essential component of diffusion models - turning latent representations into images or videos. + +## Memory + +These tables demonstrate the VRAM requirements for VAE decode with SD v1 and SD XL on different GPUs. + +For the majority of these GPUs the memory usage % dictates other models (text encoders, UNet/Transformer) must be offloaded, or tiled decoding has to be used which increases time taken and impacts quality. + +
SD v1.5 + +| GPU | Resolution | Time (seconds) | Memory (%) | Tiled Time (secs) | Tiled Memory (%) | +| --- | --- | --- | --- | --- | --- | +| NVIDIA GeForce RTX 4090 | 512x512 | 0.031 | 5.60% | 0.031 (0%) | 5.60% | +| NVIDIA GeForce RTX 4090 | 1024x1024 | 0.148 | 20.00% | 0.301 (+103%) | 5.60% | +| NVIDIA GeForce RTX 4080 | 512x512 | 0.05 | 8.40% | 0.050 (0%) | 8.40% | +| NVIDIA GeForce RTX 4080 | 1024x1024 | 0.224 | 30.00% | 0.356 (+59%) | 8.40% | +| NVIDIA GeForce RTX 4070 Ti | 512x512 | 0.066 | 11.30% | 0.066 (0%) | 11.30% | +| NVIDIA GeForce RTX 4070 Ti | 1024x1024 | 0.284 | 40.50% | 0.454 (+60%) | 11.40% | +| NVIDIA GeForce RTX 3090 | 512x512 | 0.062 | 5.20% | 0.062 (0%) | 5.20% | +| NVIDIA GeForce RTX 3090 | 1024x1024 | 0.253 | 18.50% | 0.464 (+83%) | 5.20% | +| NVIDIA GeForce RTX 3080 | 512x512 | 0.07 | 12.80% | 0.070 (0%) | 12.80% | +| NVIDIA GeForce RTX 3080 | 1024x1024 | 0.286 | 45.30% | 0.466 (+63%) | 12.90% | +| NVIDIA GeForce RTX 3070 | 512x512 | 0.102 | 15.90% | 0.102 (0%) | 15.90% | +| NVIDIA GeForce RTX 3070 | 1024x1024 | 0.421 | 56.30% | 0.746 (+77%) | 16.00% | + +
+ +
SDXL + +| GPU | Resolution | Time (seconds) | Memory Consumed (%) | Tiled Time (seconds) | Tiled Memory (%) | +| --- | --- | --- | --- | --- | --- | +| NVIDIA GeForce RTX 4090 | 512x512 | 0.057 | 10.00% | 0.057 (0%) | 10.00% | +| NVIDIA GeForce RTX 4090 | 1024x1024 | 0.256 | 35.50% | 0.257 (+0.4%) | 35.50% | +| NVIDIA GeForce RTX 4080 | 512x512 | 0.092 | 15.00% | 0.092 (0%) | 15.00% | +| NVIDIA GeForce RTX 4080 | 1024x1024 | 0.406 | 53.30% | 0.406 (0%) | 53.30% | +| NVIDIA GeForce RTX 4070 Ti | 512x512 | 0.121 | 20.20% | 0.120 (-0.8%) | 20.20% | +| NVIDIA GeForce RTX 4070 Ti | 1024x1024 | 0.519 | 72.00% | 0.519 (0%) | 72.00% | +| NVIDIA GeForce RTX 3090 | 512x512 | 0.107 | 10.50% | 0.107 (0%) | 10.50% | +| NVIDIA GeForce RTX 3090 | 1024x1024 | 0.459 | 38.00% | 0.460 (+0.2%) | 38.00% | +| NVIDIA GeForce RTX 3080 | 512x512 | 0.121 | 25.60% | 0.121 (0%) | 25.60% | +| NVIDIA GeForce RTX 3080 | 1024x1024 | 0.524 | 93.00% | 0.524 (0%) | 93.00% | +| NVIDIA GeForce RTX 3070 | 512x512 | 0.183 | 31.80% | 0.183 (0%) | 31.80% | +| NVIDIA GeForce RTX 3070 | 1024x1024 | 0.794 | 96.40% | 0.794 (0%) | 96.40% | + +
+ +## Available VAEs + +| | **Endpoint** | **Model** | +|:-:|:-----------:|:--------:| +| **Stable Diffusion v1** | [https://q1bj3bpq6kzilnsu.us-east-1.aws.endpoints.huggingface.cloud](https://q1bj3bpq6kzilnsu.us-east-1.aws.endpoints.huggingface.cloud) | [`stabilityai/sd-vae-ft-mse`](https://hf.co/stabilityai/sd-vae-ft-mse) | +| **Stable Diffusion XL** | [https://x2dmsqunjd6k9prw.us-east-1.aws.endpoints.huggingface.cloud](https://x2dmsqunjd6k9prw.us-east-1.aws.endpoints.huggingface.cloud) | [`madebyollin/sdxl-vae-fp16-fix`](https://hf.co/madebyollin/sdxl-vae-fp16-fix) | +| **Flux** | [https://whhx50ex1aryqvw6.us-east-1.aws.endpoints.huggingface.cloud](https://whhx50ex1aryqvw6.us-east-1.aws.endpoints.huggingface.cloud) | [`black-forest-labs/FLUX.1-schnell`](https://hf.co/black-forest-labs/FLUX.1-schnell) | +| **HunyuanVideo** | [https://o7ywnmrahorts457.us-east-1.aws.endpoints.huggingface.cloud](https://o7ywnmrahorts457.us-east-1.aws.endpoints.huggingface.cloud) | [`hunyuanvideo-community/HunyuanVideo`](https://hf.co/hunyuanvideo-community/HunyuanVideo) | + + +> [!TIP] +> Model support can be requested [here](https://github.com/huggingface/diffusers/issues/new?template=remote-vae-pilot-feedback.yml). + + +## Code + +> [!TIP] +> Install `diffusers` from `main` to run the code: `pip install git+https://github.com/huggingface/diffusers@main` + + +A helper method simplifies interacting with Hybrid Inference. + +```python +from diffusers.utils.remote_utils import remote_decode +``` + +### Basic example + +Here, we show how to use the remote VAE on random tensors. + +
Code + +```python +image = remote_decode( + endpoint="https://q1bj3bpq6kzilnsu.us-east-1.aws.endpoints.huggingface.cloud/", + tensor=torch.randn([1, 4, 64, 64], dtype=torch.float16), + scaling_factor=0.18215, +) +``` + +
+ +
+ +
+ +Usage for Flux is slightly different. Flux latents are packed so we need to send the `height` and `width`. + +
Code + +```python +image = remote_decode( + endpoint="https://whhx50ex1aryqvw6.us-east-1.aws.endpoints.huggingface.cloud/", + tensor=torch.randn([1, 4096, 64], dtype=torch.float16), + height=1024, + width=1024, + scaling_factor=0.3611, + shift_factor=0.1159, +) +``` + +
+ +
+ +
+ +Finally, an example for HunyuanVideo. + +
Code + +```python +video = remote_decode( + endpoint="https://o7ywnmrahorts457.us-east-1.aws.endpoints.huggingface.cloud/", + tensor=torch.randn([1, 16, 3, 40, 64], dtype=torch.float16), + output_type="mp4", +) +with open("video.mp4", "wb") as f: + f.write(video) +``` + +
+ +
+ +
+ + +### Generation + +But we want to use the VAE on an actual pipeline to get an actual image, not random noise. The example below shows how to do it with SD v1.5. + +
Code + +```python +from diffusers import StableDiffusionPipeline + +pipe = StableDiffusionPipeline.from_pretrained( + "stable-diffusion-v1-5/stable-diffusion-v1-5", + torch_dtype=torch.float16, + variant="fp16", + vae=None, +).to("cuda") + +prompt = "Strawberry ice cream, in a stylish modern glass, coconut, splashing milk cream and honey, in a gradient purple background, fluid motion, dynamic movement, cinematic lighting, Mysterious" + +latent = pipe( + prompt=prompt, + output_type="latent", +).images +image = remote_decode( + endpoint="https://q1bj3bpq6kzilnsu.us-east-1.aws.endpoints.huggingface.cloud/", + tensor=latent, + scaling_factor=0.18215, +) +image.save("test.jpg") +``` + +
+ +
+ +
+ +Here’s another example with Flux. + +
Code + +```python +from diffusers import FluxPipeline + +pipe = FluxPipeline.from_pretrained( + "black-forest-labs/FLUX.1-schnell", + torch_dtype=torch.bfloat16, + vae=None, +).to("cuda") + +prompt = "Strawberry ice cream, in a stylish modern glass, coconut, splashing milk cream and honey, in a gradient purple background, fluid motion, dynamic movement, cinematic lighting, Mysterious" + +latent = pipe( + prompt=prompt, + guidance_scale=0.0, + num_inference_steps=4, + output_type="latent", +).images +image = remote_decode( + endpoint="https://whhx50ex1aryqvw6.us-east-1.aws.endpoints.huggingface.cloud/", + tensor=latent, + height=1024, + width=1024, + scaling_factor=0.3611, + shift_factor=0.1159, +) +image.save("test.jpg") +``` + +
+ +
+ +
+ +Here’s an example with HunyuanVideo. + +
Code + +```python +from diffusers import HunyuanVideoPipeline, HunyuanVideoTransformer3DModel + +model_id = "hunyuanvideo-community/HunyuanVideo" +transformer = HunyuanVideoTransformer3DModel.from_pretrained( + model_id, subfolder="transformer", torch_dtype=torch.bfloat16 +) +pipe = HunyuanVideoPipeline.from_pretrained( + model_id, transformer=transformer, vae=None, torch_dtype=torch.float16 +).to("cuda") + +latent = pipe( + prompt="A cat walks on the grass, realistic", + height=320, + width=512, + num_frames=61, + num_inference_steps=30, + output_type="latent", +).frames + +video = remote_decode( + endpoint="https://o7ywnmrahorts457.us-east-1.aws.endpoints.huggingface.cloud/", + tensor=latent, + output_type="mp4", +) + +if isinstance(video, bytes): + with open("video.mp4", "wb") as f: + f.write(video) +``` + +
+ +
+ +
+ + +### Queueing + +One of the great benefits of using a remote VAE is that we can queue multiple generation requests. While the current latent is being processed for decoding, we can already queue another one. This helps improve concurrency. + + +
Code + +```python +import queue +import threading +from IPython.display import display +from diffusers import StableDiffusionPipeline + +def decode_worker(q: queue.Queue): + while True: + item = q.get() + if item is None: + break + image = remote_decode( + endpoint="https://q1bj3bpq6kzilnsu.us-east-1.aws.endpoints.huggingface.cloud/", + tensor=item, + scaling_factor=0.18215, + ) + display(image) + q.task_done() + +q = queue.Queue() +thread = threading.Thread(target=decode_worker, args=(q,), daemon=True) +thread.start() + +def decode(latent: torch.Tensor): + q.put(latent) + +prompts = [ + "Blueberry ice cream, in a stylish modern glass , ice cubes, nuts, mint leaves, splashing milk cream, in a gradient purple background, fluid motion, dynamic movement, cinematic lighting, Mysterious", + "Lemonade in a glass, mint leaves, in an aqua and white background, flowers, ice cubes, halo, fluid motion, dynamic movement, soft lighting, digital painting, rule of thirds composition, Art by Greg rutkowski, Coby whitmore", + "Comic book art, beautiful, vintage, pastel neon colors, extremely detailed pupils, delicate features, light on face, slight smile, Artgerm, Mary Blair, Edmund Dulac, long dark locks, bangs, glowing, fashionable style, fairytale ambience, hot pink.", + "Masterpiece, vanilla cone ice cream garnished with chocolate syrup, crushed nuts, choco flakes, in a brown background, gold, cinematic lighting, Art by WLOP", + "A bowl of milk, falling cornflakes, berries, blueberries, in a white background, soft lighting, intricate details, rule of thirds, octane render, volumetric lighting", + "Cold Coffee with cream, crushed almonds, in a glass, choco flakes, ice cubes, wet, in a wooden background, cinematic lighting, hyper realistic painting, art by Carne Griffiths, octane render, volumetric lighting, fluid motion, dynamic movement, muted colors,", +] + +pipe = StableDiffusionPipeline.from_pretrained( + "Lykon/dreamshaper-8", + torch_dtype=torch.float16, + vae=None, +).to("cuda") + +pipe.unet = pipe.unet.to(memory_format=torch.channels_last) +pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True) + +_ = pipe( + prompt=prompts[0], + output_type="latent", +) + +for prompt in prompts: + latent = pipe( + prompt=prompt, + output_type="latent", + ).images + decode(latent) + +q.put(None) +thread.join() +``` + +
+ + +
+ +
+ +## Integrations + +* **[SD.Next](https://github.com/vladmandic/sdnext):** All-in-one UI with direct supports Hybrid Inference. +* **[ComfyUI-HFRemoteVae](https://github.com/kijai/ComfyUI-HFRemoteVae):** ComfyUI node for Hybrid Inference. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/hybrid_inference/vae_encode.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/hybrid_inference/vae_encode.md new file mode 100644 index 0000000000000000000000000000000000000000..dd285fa25c03339e417934e320fabff61107a308 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/hybrid_inference/vae_encode.md @@ -0,0 +1,183 @@ +# Getting Started: VAE Encode with Hybrid Inference + +VAE encode is used for training, image-to-image and image-to-video - turning into images or videos into latent representations. + +## Memory + +These tables demonstrate the VRAM requirements for VAE encode with SD v1 and SD XL on different GPUs. + +For the majority of these GPUs the memory usage % dictates other models (text encoders, UNet/Transformer) must be offloaded, or tiled encoding has to be used which increases time taken and impacts quality. + +
SD v1.5 + +| GPU | Resolution | Time (seconds) | Memory (%) | Tiled Time (secs) | Tiled Memory (%) | +|:------------------------------|:-------------|-----------------:|-------------:|--------------------:|-------------------:| +| NVIDIA GeForce RTX 4090 | 512x512 | 0.015 | 3.51901 | 0.015 | 3.51901 | +| NVIDIA GeForce RTX 4090 | 256x256 | 0.004 | 1.3154 | 0.005 | 1.3154 | +| NVIDIA GeForce RTX 4090 | 2048x2048 | 0.402 | 47.1852 | 0.496 | 3.51901 | +| NVIDIA GeForce RTX 4090 | 1024x1024 | 0.078 | 12.2658 | 0.094 | 3.51901 | +| NVIDIA GeForce RTX 4080 SUPER | 512x512 | 0.023 | 5.30105 | 0.023 | 5.30105 | +| NVIDIA GeForce RTX 4080 SUPER | 256x256 | 0.006 | 1.98152 | 0.006 | 1.98152 | +| NVIDIA GeForce RTX 4080 SUPER | 2048x2048 | 0.574 | 71.08 | 0.656 | 5.30105 | +| NVIDIA GeForce RTX 4080 SUPER | 1024x1024 | 0.111 | 18.4772 | 0.14 | 5.30105 | +| NVIDIA GeForce RTX 3090 | 512x512 | 0.032 | 3.52782 | 0.032 | 3.52782 | +| NVIDIA GeForce RTX 3090 | 256x256 | 0.01 | 1.31869 | 0.009 | 1.31869 | +| NVIDIA GeForce RTX 3090 | 2048x2048 | 0.742 | 47.3033 | 0.954 | 3.52782 | +| NVIDIA GeForce RTX 3090 | 1024x1024 | 0.136 | 12.2965 | 0.207 | 3.52782 | +| NVIDIA GeForce RTX 3080 | 512x512 | 0.036 | 8.51761 | 0.036 | 8.51761 | +| NVIDIA GeForce RTX 3080 | 256x256 | 0.01 | 3.18387 | 0.01 | 3.18387 | +| NVIDIA GeForce RTX 3080 | 2048x2048 | 0.863 | 86.7424 | 1.191 | 8.51761 | +| NVIDIA GeForce RTX 3080 | 1024x1024 | 0.157 | 29.6888 | 0.227 | 8.51761 | +| NVIDIA GeForce RTX 3070 | 512x512 | 0.051 | 10.6941 | 0.051 | 10.6941 | +| NVIDIA GeForce RTX 3070 | 256x256 | 0.015 | 3.99743 | 0.015 | 3.99743 | +| NVIDIA GeForce RTX 3070 | 2048x2048 | 1.217 | 96.054 | 1.482 | 10.6941 | +| NVIDIA GeForce RTX 3070 | 1024x1024 | 0.223 | 37.2751 | 0.327 | 10.6941 | + + +
+ +
SDXL + +| GPU | Resolution | Time (seconds) | Memory Consumed (%) | Tiled Time (seconds) | Tiled Memory (%) | +|:------------------------------|:-------------|-----------------:|----------------------:|-----------------------:|-------------------:| +| NVIDIA GeForce RTX 4090 | 512x512 | 0.029 | 4.95707 | 0.029 | 4.95707 | +| NVIDIA GeForce RTX 4090 | 256x256 | 0.007 | 2.29666 | 0.007 | 2.29666 | +| NVIDIA GeForce RTX 4090 | 2048x2048 | 0.873 | 66.3452 | 0.863 | 15.5649 | +| NVIDIA GeForce RTX 4090 | 1024x1024 | 0.142 | 15.5479 | 0.143 | 15.5479 | +| NVIDIA GeForce RTX 4080 SUPER | 512x512 | 0.044 | 7.46735 | 0.044 | 7.46735 | +| NVIDIA GeForce RTX 4080 SUPER | 256x256 | 0.01 | 3.4597 | 0.01 | 3.4597 | +| NVIDIA GeForce RTX 4080 SUPER | 2048x2048 | 1.317 | 87.1615 | 1.291 | 23.447 | +| NVIDIA GeForce RTX 4080 SUPER | 1024x1024 | 0.213 | 23.4215 | 0.214 | 23.4215 | +| NVIDIA GeForce RTX 3090 | 512x512 | 0.058 | 5.65638 | 0.058 | 5.65638 | +| NVIDIA GeForce RTX 3090 | 256x256 | 0.016 | 2.45081 | 0.016 | 2.45081 | +| NVIDIA GeForce RTX 3090 | 2048x2048 | 1.755 | 77.8239 | 1.614 | 18.4193 | +| NVIDIA GeForce RTX 3090 | 1024x1024 | 0.265 | 18.4023 | 0.265 | 18.4023 | +| NVIDIA GeForce RTX 3080 | 512x512 | 0.064 | 13.6568 | 0.064 | 13.6568 | +| NVIDIA GeForce RTX 3080 | 256x256 | 0.018 | 5.91728 | 0.018 | 5.91728 | +| NVIDIA GeForce RTX 3080 | 2048x2048 | OOM | OOM | 1.866 | 44.4717 | +| NVIDIA GeForce RTX 3080 | 1024x1024 | 0.302 | 44.4308 | 0.302 | 44.4308 | +| NVIDIA GeForce RTX 3070 | 512x512 | 0.093 | 17.1465 | 0.093 | 17.1465 | +| NVIDIA GeForce RTX 3070 | 256x256 | 0.025 | 7.42931 | 0.026 | 7.42931 | +| NVIDIA GeForce RTX 3070 | 2048x2048 | OOM | OOM | 2.674 | 55.8355 | +| NVIDIA GeForce RTX 3070 | 1024x1024 | 0.443 | 55.7841 | 0.443 | 55.7841 | + +
+ +## Available VAEs + +| | **Endpoint** | **Model** | +|:-:|:-----------:|:--------:| +| **Stable Diffusion v1** | [https://qc6479g0aac6qwy9.us-east-1.aws.endpoints.huggingface.cloud](https://qc6479g0aac6qwy9.us-east-1.aws.endpoints.huggingface.cloud) | [`stabilityai/sd-vae-ft-mse`](https://hf.co/stabilityai/sd-vae-ft-mse) | +| **Stable Diffusion XL** | [https://xjqqhmyn62rog84g.us-east-1.aws.endpoints.huggingface.cloud](https://xjqqhmyn62rog84g.us-east-1.aws.endpoints.huggingface.cloud) | [`madebyollin/sdxl-vae-fp16-fix`](https://hf.co/madebyollin/sdxl-vae-fp16-fix) | +| **Flux** | [https://ptccx55jz97f9zgo.us-east-1.aws.endpoints.huggingface.cloud](https://ptccx55jz97f9zgo.us-east-1.aws.endpoints.huggingface.cloud) | [`black-forest-labs/FLUX.1-schnell`](https://hf.co/black-forest-labs/FLUX.1-schnell) | + + +> [!TIP] +> Model support can be requested [here](https://github.com/huggingface/diffusers/issues/new?template=remote-vae-pilot-feedback.yml). + + +## Code + +> [!TIP] +> Install `diffusers` from `main` to run the code: `pip install git+https://github.com/huggingface/diffusers@main` + + +A helper method simplifies interacting with Hybrid Inference. + +```python +from diffusers.utils.remote_utils import remote_encode +``` + +### Basic example + +Let's encode an image, then decode it to demonstrate. + +
+ +
+ +
Code + +```python +from diffusers.utils import load_image +from diffusers.utils.remote_utils import remote_decode + +image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/astronaut.jpg?download=true") + +latent = remote_encode( + endpoint="https://ptccx55jz97f9zgo.us-east-1.aws.endpoints.huggingface.cloud/", + scaling_factor=0.3611, + shift_factor=0.1159, +) + +decoded = remote_decode( + endpoint="https://whhx50ex1aryqvw6.us-east-1.aws.endpoints.huggingface.cloud/", + tensor=latent, + scaling_factor=0.3611, + shift_factor=0.1159, +) +``` + +
+ +
+ +
+ + +### Generation + +Now let's look at a generation example, we'll encode the image, generate then remotely decode too! + +
Code + +```python +import torch +from diffusers import StableDiffusionImg2ImgPipeline +from diffusers.utils import load_image +from diffusers.utils.remote_utils import remote_decode, remote_encode + +pipe = StableDiffusionImg2ImgPipeline.from_pretrained( + "stable-diffusion-v1-5/stable-diffusion-v1-5", + torch_dtype=torch.float16, + variant="fp16", + vae=None, +).to("cuda") + +init_image = load_image( + "https://raw.githubusercontent.com/CompVis/stable-diffusion/main/assets/stable-samples/img2img/sketch-mountains-input.jpg" +) +init_image = init_image.resize((768, 512)) + +init_latent = remote_encode( + endpoint="https://qc6479g0aac6qwy9.us-east-1.aws.endpoints.huggingface.cloud/", + image=init_image, + scaling_factor=0.18215, +) + +prompt = "A fantasy landscape, trending on artstation" +latent = pipe( + prompt=prompt, + image=init_latent, + strength=0.75, + output_type="latent", +).images + +image = remote_decode( + endpoint="https://q1bj3bpq6kzilnsu.us-east-1.aws.endpoints.huggingface.cloud/", + tensor=latent, + scaling_factor=0.18215, +) +image.save("fantasy_landscape.jpg") +``` + +
+ +
+ +
+ +## Integrations + +* **[SD.Next](https://github.com/vladmandic/sdnext):** All-in-one UI with direct supports Hybrid Inference. +* **[ComfyUI-HFRemoteVae](https://github.com/kijai/ComfyUI-HFRemoteVae):** ComfyUI node for Hybrid Inference. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/imgs/access_request.png b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/imgs/access_request.png new file mode 100644 index 0000000000000000000000000000000000000000..1a19908c64bd08dcba67f10375813d2821bf6f66 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/imgs/access_request.png @@ -0,0 +1,3 @@ +version https://git-lfs.github.com/spec/v1 +oid sha256:9688dabf75e180590251cd1f75d18966f9c94d5d6584bc7d0278b698c175c61f +size 104814 diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/imgs/diffusers_library.jpg b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/imgs/diffusers_library.jpg new file mode 100644 index 0000000000000000000000000000000000000000..c2f8c529a69d4e01f4601bfc435ae90b24659fca --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/imgs/diffusers_library.jpg @@ -0,0 +1,3 @@ +version https://git-lfs.github.com/spec/v1 +oid sha256:be2485d6656bec11b85f469b2bc04736a8de8270fa2f3779d9d40bfab3966950 +size 14061 diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/index.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/index.md new file mode 100644 index 0000000000000000000000000000000000000000..957d90786dd796f5b1b7f75c6db84aeb7e26cf63 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/index.md @@ -0,0 +1,48 @@ + + +

+
+ +
+

+ +# Diffusers + +🤗 Diffusers is the go-to library for state-of-the-art pretrained diffusion models for generating images, audio, and even 3D structures of molecules. Whether you're looking for a simple inference solution or want to train your own diffusion model, 🤗 Diffusers is a modular toolbox that supports both. Our library is designed with a focus on [usability over performance](conceptual/philosophy#usability-over-performance), [simple over easy](conceptual/philosophy#simple-over-easy), and [customizability over abstractions](conceptual/philosophy#tweakable-contributorfriendly-over-abstraction). + +The library has three main components: + +- State-of-the-art diffusion pipelines for inference with just a few lines of code. There are many pipelines in 🤗 Diffusers, check out the table in the pipeline [overview](api/pipelines/overview) for a complete list of available pipelines and the task they solve. +- Interchangeable [noise schedulers](api/schedulers/overview) for balancing trade-offs between generation speed and quality. +- Pretrained [models](api/models) that can be used as building blocks, and combined with schedulers, for creating your own end-to-end diffusion systems. + + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/installation.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/installation.md new file mode 100644 index 0000000000000000000000000000000000000000..570fac096862ecb214c92945c80430b141a1a54e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/installation.md @@ -0,0 +1,194 @@ + + +# Installation + +🤗 Diffusers is tested on Python 3.8+, PyTorch 1.7.0+, and Flax. Follow the installation instructions below for the deep learning library you are using: + +- [PyTorch](https://pytorch.org/get-started/locally/) installation instructions +- [Flax](https://flax.readthedocs.io/en/latest/) installation instructions + +## Install with pip + +You should install 🤗 Diffusers in a [virtual environment](https://docs.python.org/3/library/venv.html). +If you're unfamiliar with Python virtual environments, take a look at this [guide](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/). +A virtual environment makes it easier to manage different projects and avoid compatibility issues between dependencies. + +Create a virtual environment with Python or [uv](https://docs.astral.sh/uv/) (refer to [Installation](https://docs.astral.sh/uv/getting-started/installation/) for installation instructions), a fast Rust-based Python package and project manager. + + + + +```bash +uv venv my-env +source my-env/bin/activate +``` + + + + +```bash +python -m venv my-env +source my-env/bin/activate +``` + + + + +You should also install 🤗 Transformers because 🤗 Diffusers relies on its models. + + + + + +PyTorch only supports Python 3.8 - 3.11 on Windows. Install Diffusers with uv. + +```bash +uv install diffusers["torch"] transformers +``` + +You can also install Diffusers with pip. + +```bash +pip install diffusers["torch"] transformers +``` + + + + +Install Diffusers with uv. + +```bash +uv pip install diffusers["flax"] transformers +``` + +You can also install Diffusers with pip. + +```bash +pip install diffusers["flax"] transformers +``` + + + + +## Install with conda + +After activating your virtual environment, with `conda` (maintained by the community): + +```bash +conda install -c conda-forge diffusers +``` + +## Install from source + +Before installing 🤗 Diffusers from source, make sure you have PyTorch and 🤗 Accelerate installed. + +To install 🤗 Accelerate: + +```bash +pip install accelerate +``` + +Then install 🤗 Diffusers from source: + +```bash +pip install git+https://github.com/huggingface/diffusers +``` + +This command installs the bleeding edge `main` version rather than the latest `stable` version. +The `main` version is useful for staying up-to-date with the latest developments. +For instance, if a bug has been fixed since the last official release but a new release hasn't been rolled out yet. +However, this means the `main` version may not always be stable. +We strive to keep the `main` version operational, and most issues are usually resolved within a few hours or a day. +If you run into a problem, please open an [Issue](https://github.com/huggingface/diffusers/issues/new/choose) so we can fix it even sooner! + +## Editable install + +You will need an editable install if you'd like to: + +* Use the `main` version of the source code. +* Contribute to 🤗 Diffusers and need to test changes in the code. + +Clone the repository and install 🤗 Diffusers with the following commands: + +```bash +git clone https://github.com/huggingface/diffusers.git +cd diffusers +``` + + + +```bash +pip install -e ".[torch]" +``` + + +```bash +pip install -e ".[flax]" +``` + + + +These commands will link the folder you cloned the repository to and your Python library paths. +Python will now look inside the folder you cloned to in addition to the normal library paths. +For example, if your Python packages are typically installed in `~/anaconda3/envs/main/lib/python3.10/site-packages/`, Python will also search the `~/diffusers/` folder you cloned to. + + + +You must keep the `diffusers` folder if you want to keep using the library. + + + +Now you can easily update your clone to the latest version of 🤗 Diffusers with the following command: + +```bash +cd ~/diffusers/ +git pull +``` + +Your Python environment will find the `main` version of 🤗 Diffusers on the next run. + +## Cache + +Model weights and files are downloaded from the Hub to a cache which is usually your home directory. You can change the cache location by specifying the `HF_HOME` or `HUGGINFACE_HUB_CACHE` environment variables or configuring the `cache_dir` parameter in methods like [`~DiffusionPipeline.from_pretrained`]. + +Cached files allow you to run 🤗 Diffusers offline. To prevent 🤗 Diffusers from connecting to the internet, set the `HF_HUB_OFFLINE` environment variable to `1` and 🤗 Diffusers will only load previously downloaded files in the cache. + +```shell +export HF_HUB_OFFLINE=1 +``` + +For more details about managing and cleaning the cache, take a look at the [caching](https://huggingface.co/docs/huggingface_hub/guides/manage-cache) guide. + +## Telemetry logging + +Our library gathers telemetry information during [`~DiffusionPipeline.from_pretrained`] requests. +The data gathered includes the version of 🤗 Diffusers and PyTorch/Flax, the requested model or pipeline class, +and the path to a pretrained checkpoint if it is hosted on the Hugging Face Hub. +This usage data helps us debug issues and prioritize new features. +Telemetry is only sent when loading models and pipelines from the Hub, +and it is not collected if you're loading local files. + +We understand that not everyone wants to share additional information,and we respect your privacy. +You can disable telemetry collection by setting the `HF_HUB_DISABLE_TELEMETRY` environment variable from your terminal: + +On Linux/MacOS: + +```bash +export HF_HUB_DISABLE_TELEMETRY=1 +``` + +On Windows: + +```bash +set HF_HUB_DISABLE_TELEMETRY=1 +``` diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/coreml.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/coreml.md new file mode 100644 index 0000000000000000000000000000000000000000..d090ef0ed3ba76ea2877669820ff908f51d52d44 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/coreml.md @@ -0,0 +1,164 @@ + + +# How to run Stable Diffusion with Core ML + +[Core ML](https://developer.apple.com/documentation/coreml) is the model format and machine learning library supported by Apple frameworks. If you are interested in running Stable Diffusion models inside your macOS or iOS/iPadOS apps, this guide will show you how to convert existing PyTorch checkpoints into the Core ML format and use them for inference with Python or Swift. + +Core ML models can leverage all the compute engines available in Apple devices: the CPU, the GPU, and the Apple Neural Engine (or ANE, a tensor-optimized accelerator available in Apple Silicon Macs and modern iPhones/iPads). Depending on the model and the device it's running on, Core ML can mix and match compute engines too, so some portions of the model may run on the CPU while others run on GPU, for example. + + + +You can also run the `diffusers` Python codebase on Apple Silicon Macs using the `mps` accelerator built into PyTorch. This approach is explained in depth in [the mps guide](mps), but it is not compatible with native apps. + + + +## Stable Diffusion Core ML Checkpoints + +Stable Diffusion weights (or checkpoints) are stored in the PyTorch format, so you need to convert them to the Core ML format before we can use them inside native apps. + +Thankfully, Apple engineers developed [a conversion tool](https://github.com/apple/ml-stable-diffusion#-converting-models-to-core-ml) based on `diffusers` to convert the PyTorch checkpoints to Core ML. + +Before you convert a model, though, take a moment to explore the Hugging Face Hub – chances are the model you're interested in is already available in Core ML format: + +- the [Apple](https://huggingface.co/apple) organization includes Stable Diffusion versions 1.4, 1.5, 2.0 base, and 2.1 base +- [coreml community](https://huggingface.co/coreml-community) includes custom finetuned models +- use this [filter](https://huggingface.co/models?pipeline_tag=text-to-image&library=coreml&p=2&sort=likes) to return all available Core ML checkpoints + +If you can't find the model you're interested in, we recommend you follow the instructions for [Converting Models to Core ML](https://github.com/apple/ml-stable-diffusion#-converting-models-to-core-ml) by Apple. + +## Selecting the Core ML Variant to Use + +Stable Diffusion models can be converted to different Core ML variants intended for different purposes: + +- The type of attention blocks used. The attention operation is used to "pay attention" to the relationship between different areas in the image representations and to understand how the image and text representations are related. Attention is compute- and memory-intensive, so different implementations exist that consider the hardware characteristics of different devices. For Core ML Stable Diffusion models, there are two attention variants: + * `split_einsum` ([introduced by Apple](https://machinelearning.apple.com/research/neural-engine-transformers)) is optimized for ANE devices, which is available in modern iPhones, iPads and M-series computers. + * The "original" attention (the base implementation used in `diffusers`) is only compatible with CPU/GPU and not ANE. It can be *faster* to run your model on CPU + GPU using `original` attention than ANE. See [this performance benchmark](https://huggingface.co/blog/fast-mac-diffusers#performance-benchmarks) as well as some [additional measures provided by the community](https://github.com/huggingface/swift-coreml-diffusers/issues/31) for additional details. + +- The supported inference framework. + * `packages` are suitable for Python inference. This can be used to test converted Core ML models before attempting to integrate them inside native apps, or if you want to explore Core ML performance but don't need to support native apps. For example, an application with a web UI could perfectly use a Python Core ML backend. + * `compiled` models are required for Swift code. The `compiled` models in the Hub split the large UNet model weights into several files for compatibility with iOS and iPadOS devices. This corresponds to the [`--chunk-unet` conversion option](https://github.com/apple/ml-stable-diffusion#-converting-models-to-core-ml). If you want to support native apps, then you need to select the `compiled` variant. + +The official Core ML Stable Diffusion [models](https://huggingface.co/apple/coreml-stable-diffusion-v1-4/tree/main) include these variants, but the community ones may vary: + +``` +coreml-stable-diffusion-v1-4 +├── README.md +├── original +│ ├── compiled +│ └── packages +└── split_einsum + ├── compiled + └── packages +``` + +You can download and use the variant you need as shown below. + +## Core ML Inference in Python + +Install the following libraries to run Core ML inference in Python: + +```bash +pip install huggingface_hub +pip install git+https://github.com/apple/ml-stable-diffusion +``` + +### Download the Model Checkpoints + +To run inference in Python, use one of the versions stored in the `packages` folders because the `compiled` ones are only compatible with Swift. You may choose whether you want to use `original` or `split_einsum` attention. + +This is how you'd download the `original` attention variant from the Hub to a directory called `models`: + +```Python +from huggingface_hub import snapshot_download +from pathlib import Path + +repo_id = "apple/coreml-stable-diffusion-v1-4" +variant = "original/packages" + +model_path = Path("./models") / (repo_id.split("/")[-1] + "_" + variant.replace("/", "_")) +snapshot_download(repo_id, allow_patterns=f"{variant}/*", local_dir=model_path, local_dir_use_symlinks=False) +print(f"Model downloaded at {model_path}") +``` + +### Inference[[python-inference]] + +Once you have downloaded a snapshot of the model, you can test it using Apple's Python script. + +```shell +python -m python_coreml_stable_diffusion.pipeline --prompt "a photo of an astronaut riding a horse on mars" -i ./models/coreml-stable-diffusion-v1-4_original_packages/original/packages -o --compute-unit CPU_AND_GPU --seed 93 +``` + +Pass the path of the downloaded checkpoint with `-i` flag to the script. `--compute-unit` indicates the hardware you want to allow for inference. It must be one of the following options: `ALL`, `CPU_AND_GPU`, `CPU_ONLY`, `CPU_AND_NE`. You may also provide an optional output path, and a seed for reproducibility. + +The inference script assumes you're using the original version of the Stable Diffusion model, `CompVis/stable-diffusion-v1-4`. If you use another model, you *have* to specify its Hub id in the inference command line, using the `--model-version` option. This works for models already supported and custom models you trained or fine-tuned yourself. + +For example, if you want to use [`stable-diffusion-v1-5/stable-diffusion-v1-5`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5): + +```shell +python -m python_coreml_stable_diffusion.pipeline --prompt "a photo of an astronaut riding a horse on mars" --compute-unit ALL -o output --seed 93 -i models/coreml-stable-diffusion-v1-5_original_packages --model-version stable-diffusion-v1-5/stable-diffusion-v1-5 +``` + +## Core ML inference in Swift + +Running inference in Swift is slightly faster than in Python because the models are already compiled in the `mlmodelc` format. This is noticeable on app startup when the model is loaded but shouldn’t be noticeable if you run several generations afterward. + +### Download + +To run inference in Swift on your Mac, you need one of the `compiled` checkpoint versions. We recommend you download them locally using Python code similar to the previous example, but with one of the `compiled` variants: + +```Python +from huggingface_hub import snapshot_download +from pathlib import Path + +repo_id = "apple/coreml-stable-diffusion-v1-4" +variant = "original/compiled" + +model_path = Path("./models") / (repo_id.split("/")[-1] + "_" + variant.replace("/", "_")) +snapshot_download(repo_id, allow_patterns=f"{variant}/*", local_dir=model_path, local_dir_use_symlinks=False) +print(f"Model downloaded at {model_path}") +``` + +### Inference[[swift-inference]] + +To run inference, please clone Apple's repo: + +```bash +git clone https://github.com/apple/ml-stable-diffusion +cd ml-stable-diffusion +``` + +And then use Apple's command line tool, [Swift Package Manager](https://www.swift.org/package-manager/#): + +```bash +swift run StableDiffusionSample --resource-path models/coreml-stable-diffusion-v1-4_original_compiled --compute-units all "a photo of an astronaut riding a horse on mars" +``` + +You have to specify in `--resource-path` one of the checkpoints downloaded in the previous step, so please make sure it contains compiled Core ML bundles with the extension `.mlmodelc`. The `--compute-units` has to be one of these values: `all`, `cpuOnly`, `cpuAndGPU`, `cpuAndNeuralEngine`. + +For more details, please refer to the [instructions in Apple's repo](https://github.com/apple/ml-stable-diffusion). + +## Supported Diffusers Features + +The Core ML models and inference code don't support many of the features, options, and flexibility of 🧨 Diffusers. These are some of the limitations to keep in mind: + +- Core ML models are only suitable for inference. They can't be used for training or fine-tuning. +- Only two schedulers have been ported to Swift, the default one used by Stable Diffusion and `DPMSolverMultistepScheduler`, which we ported to Swift from our `diffusers` implementation. We recommend you use `DPMSolverMultistepScheduler`, since it produces the same quality in about half the steps. +- Negative prompts, classifier-free guidance scale, and image-to-image tasks are available in the inference code. Advanced features such as depth guidance, ControlNet, and latent upscalers are not available yet. + +Apple's [conversion and inference repo](https://github.com/apple/ml-stable-diffusion) and our own [swift-coreml-diffusers](https://github.com/huggingface/swift-coreml-diffusers) repos are intended as technology demonstrators to enable other developers to build upon. + +If you feel strongly about any missing features, please feel free to open a feature request or, better yet, a contribution PR 🙂. + +## Native Diffusers Swift app + +One easy way to run Stable Diffusion on your own Apple hardware is to use [our open-source Swift repo](https://github.com/huggingface/swift-coreml-diffusers), based on `diffusers` and Apple's conversion and inference repo. You can study the code, compile it with [Xcode](https://developer.apple.com/xcode/) and adapt it for your own needs. For your convenience, there's also a [standalone Mac app in the App Store](https://apps.apple.com/app/diffusers/id1666309574), so you can play with it without having to deal with the code or IDE. If you are a developer and have determined that Core ML is the best solution to build your Stable Diffusion app, then you can use the rest of this guide to get started with your project. We can't wait to see what you'll build 🙂. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/deepcache.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/deepcache.md new file mode 100644 index 0000000000000000000000000000000000000000..1d0e959f3a4c855b1ce300069583592a7718ea08 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/deepcache.md @@ -0,0 +1,62 @@ + + +# DeepCache +[DeepCache](https://huggingface.co/papers/2312.00858) accelerates [`StableDiffusionPipeline`] and [`StableDiffusionXLPipeline`] by strategically caching and reusing high-level features while efficiently updating low-level features by taking advantage of the U-Net architecture. + +Start by installing [DeepCache](https://github.com/horseee/DeepCache): +```bash +pip install DeepCache +``` + +Then load and enable the [`DeepCacheSDHelper`](https://github.com/horseee/DeepCache#usage): + +```diff + import torch + from diffusers import StableDiffusionPipeline + pipe = StableDiffusionPipeline.from_pretrained('stable-diffusion-v1-5/stable-diffusion-v1-5', torch_dtype=torch.float16).to("cuda") + ++ from DeepCache import DeepCacheSDHelper ++ helper = DeepCacheSDHelper(pipe=pipe) ++ helper.set_params( ++ cache_interval=3, ++ cache_branch_id=0, ++ ) ++ helper.enable() + + image = pipe("a photo of an astronaut on a moon").images[0] +``` + +The `set_params` method accepts two arguments: `cache_interval` and `cache_branch_id`. `cache_interval` means the frequency of feature caching, specified as the number of steps between each cache operation. `cache_branch_id` identifies which branch of the network (ordered from the shallowest to the deepest layer) is responsible for executing the caching processes. +Opting for a lower `cache_branch_id` or a larger `cache_interval` can lead to faster inference speed at the expense of reduced image quality (ablation experiments of these two hyperparameters can be found in the [paper](https://huggingface.co/papers/2312.00858)). Once those arguments are set, use the `enable` or `disable` methods to activate or deactivate the `DeepCacheSDHelper`. + +
+ +
+ +You can find more generated samples (original pipeline vs DeepCache) and the corresponding inference latency in the [WandB report](https://wandb.ai/horseee/DeepCache/runs/jwlsqqgt?workspace=user-horseee). The prompts are randomly selected from the [MS-COCO 2017](https://cocodataset.org/#home) dataset. + +## Benchmark + +We tested how much faster DeepCache accelerates [Stable Diffusion v2.1](https://huggingface.co/stabilityai/stable-diffusion-2-1) with 50 inference steps on an NVIDIA RTX A5000, using different configurations for resolution, batch size, cache interval (I), and cache branch (B). + +| **Resolution** | **Batch size** | **Original** | **DeepCache(I=3, B=0)** | **DeepCache(I=5, B=0)** | **DeepCache(I=5, B=1)** | +|----------------|----------------|--------------|-------------------------|-------------------------|-------------------------| +| 512| 8| 15.96| 6.88(2.32x)| 5.03(3.18x)| 7.27(2.20x)| +| | 4| 8.39| 3.60(2.33x)| 2.62(3.21x)| 3.75(2.24x)| +| | 1| 2.61| 1.12(2.33x)| 0.81(3.24x)| 1.11(2.35x)| +| 768| 8| 43.58| 18.99(2.29x)| 13.96(3.12x)| 21.27(2.05x)| +| | 4| 22.24| 9.67(2.30x)| 7.10(3.13x)| 10.74(2.07x)| +| | 1| 6.33| 2.72(2.33x)| 1.97(3.21x)| 2.98(2.12x)| +| 1024| 8| 101.95| 45.57(2.24x)| 33.72(3.02x)| 53.00(1.92x)| +| | 4| 49.25| 21.86(2.25x)| 16.19(3.04x)| 25.78(1.91x)| +| | 1| 13.83| 6.07(2.28x)| 4.43(3.12x)| 7.15(1.93x)| diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/fp16.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/fp16.md new file mode 100644 index 0000000000000000000000000000000000000000..97a1f5830a946b77909fb0c67b4048297cace856 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/fp16.md @@ -0,0 +1,220 @@ + + +# Accelerate inference + +Diffusion models are slow at inference because generation is an iterative process where noise is gradually refined into an image or video over a certain number of "steps". To speedup this process, you can try experimenting with different [schedulers](../api/schedulers/overview), reduce the precision of the model weights for faster computations, use more memory-efficient attention mechanisms, and more. + +Combine and use these techniques together to make inference faster than using any single technique on its own. + +This guide will go over how to accelerate inference. + +## Model data type + +The precision and data type of the model weights affect inference speed because a higher precision requires more memory to load and more time to perform the computations. PyTorch loads model weights in float32 or full precision by default, so changing the data type is a simple way to quickly get faster inference. + + + + +bfloat16 is similar to float16 but it is more robust to numerical errors. Hardware support for bfloat16 varies, but most modern GPUs are capable of supporting bfloat16. + +```py +import torch +from diffusers import StableDiffusionXLPipeline + +pipeline = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.bfloat16 +).to("cuda") + +prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k" +pipeline(prompt, num_inference_steps=30).images[0] +``` + + + + +float16 is similar to bfloat16 but may be more prone to numerical errors. + +```py +import torch +from diffusers import StableDiffusionXLPipeline + +pipeline = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16 +).to("cuda") + +prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k" +pipeline(prompt, num_inference_steps=30).images[0] +``` + + + + +[TensorFloat-32 (tf32)](https://blogs.nvidia.com/blog/2020/05/14/tensorfloat-32-precision-format/) mode is supported on NVIDIA Ampere GPUs and it computes the convolution and matrix multiplication operations in tf32. Storage and other operations are kept in float32. This enables significantly faster computations when combined with bfloat16 or float16. + +PyTorch only enables tf32 mode for convolutions by default and you'll need to explicitly enable it for matrix multiplications. + +```py +import torch +from diffusers import StableDiffusionXLPipeline + +torch.backends.cuda.matmul.allow_tf32 = True + +pipeline = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.bfloat16 +).to("cuda") + +prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k" +pipeline(prompt, num_inference_steps=30).images[0] +``` + +Refer to the [mixed precision training](https://huggingface.co/docs/transformers/en/perf_train_gpu_one#mixed-precision) docs for more details. + + + + +## Scaled dot product attention + +> [!TIP] +> Memory-efficient attention optimizes for inference speed *and* [memory usage](./memory#memory-efficient-attention)! + +[Scaled dot product attention (SDPA)](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html) implements several attention backends, [FlashAttention](https://github.com/Dao-AILab/flash-attention), [xFormers](https://github.com/facebookresearch/xformers), and a native C++ implementation. It automatically selects the most optimal backend for your hardware. + +SDPA is enabled by default if you're using PyTorch >= 2.0 and no additional changes are required to your code. You could try experimenting with other attention backends though if you'd like to choose your own. The example below uses the [torch.nn.attention.sdpa_kernel](https://pytorch.org/docs/stable/generated/torch.nn.attention.sdpa_kernel.html) context manager to enable efficient attention. + +```py +from torch.nn.attention import SDPBackend, sdpa_kernel +import torch +from diffusers import StableDiffusionXLPipeline + +pipeline = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.bfloat16 +).to("cuda") + +prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k" + +with sdpa_kernel(SDPBackend.EFFICIENT_ATTENTION): + image = pipeline(prompt, num_inference_steps=30).images[0] +``` + +## torch.compile + +[torch.compile](https://pytorch.org/tutorials/intermediate/torch_compile_tutorial.html) accelerates inference by compiling PyTorch code and operations into optimized kernels. Diffusers typically compiles the more compute-intensive models like the UNet, transformer, or VAE. + +Enable the following compiler settings for maximum speed (refer to the [full list](https://github.com/pytorch/pytorch/blob/main/torch/_inductor/config.py) for more options). + +```py +import torch +from diffusers import StableDiffusionXLPipeline + +torch._inductor.config.conv_1x1_as_mm = True +torch._inductor.config.coordinate_descent_tuning = True +torch._inductor.config.epilogue_fusion = False +torch._inductor.config.coordinate_descent_check_all_directions = True +``` + +Load and compile the UNet and VAE. There are several different modes you can choose from, but `"max-autotune"` optimizes for the fastest speed by compiling to a CUDA graph. CUDA graphs effectively reduces the overhead by launching multiple GPU operations through a single CPU operation. + +> [!TIP] +> With PyTorch 2.3.1, you can control the caching behavior of torch.compile. This is particularly beneficial for compilation modes like `"max-autotune"` which performs a grid-search over several compilation flags to find the optimal configuration. Learn more in the [Compile Time Caching in torch.compile](https://pytorch.org/tutorials/recipes/torch_compile_caching_tutorial.html) tutorial. + +Changing the memory layout to [channels_last](./memory#torchchannels_last) also optimizes memory and inference speed. + +```py +pipeline = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16 +).to("cuda") +pipeline.unet.to(memory_format=torch.channels_last) +pipeline.vae.to(memory_format=torch.channels_last) +pipeline.unet = torch.compile( + pipeline.unet, mode="max-autotune", fullgraph=True +) +pipeline.vae.decode = torch.compile( + pipeline.vae.decode, + mode="max-autotune", + fullgraph=True +) + +prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k" +pipeline(prompt, num_inference_steps=30).images[0] +``` + +Compilation is slow the first time, but once compiled, it is significantly faster. Try to only use the compiled pipeline on the same type of inference operations. Calling the compiled pipeline on a different image size retriggers compilation which is slow and inefficient. + +### Graph breaks + +It is important to specify `fullgraph=True` in torch.compile to ensure there are no graph breaks in the underlying model. This allows you to take advantage of torch.compile without any performance degradation. For the UNet and VAE, this changes how you access the return variables. + +```diff +- latents = unet( +- latents, timestep=timestep, encoder_hidden_states=prompt_embeds +-).sample + ++ latents = unet( ++ latents, timestep=timestep, encoder_hidden_states=prompt_embeds, return_dict=False ++)[0] +``` + +### GPU sync + +The `step()` function is [called](https://github.com/huggingface/diffusers/blob/1d686bac8146037e97f3fd8c56e4063230f71751/src/diffusers/pipelines/stable_diffusion_xl/pipeline_stable_diffusion_xl.py#L1228) on the scheduler each time after the denoiser makes a prediction, and the `sigmas` variable is [indexed](https://github.com/huggingface/diffusers/blob/1d686bac8146037e97f3fd8c56e4063230f71751/src/diffusers/schedulers/scheduling_euler_discrete.py#L476). When placed on the GPU, it introduces latency because of the communication sync between the CPU and GPU. It becomes more evident when the denoiser has already been compiled. + +In general, the `sigmas` should [stay on the CPU](https://github.com/huggingface/diffusers/blob/35a969d297cba69110d175ee79c59312b9f49e1e/src/diffusers/schedulers/scheduling_euler_discrete.py#L240) to avoid the communication sync and latency. + +## Dynamic quantization + +[Dynamic quantization](https://pytorch.org/tutorials/recipes/recipes/dynamic_quantization.html) improves inference speed by reducing precision to enable faster math operations. This particular type of quantization determines how to scale the activations based on the data at runtime rather than using a fixed scaling factor. As a result, the scaling factor is more accurately aligned with the data. + +The example below applies [dynamic int8 quantization](https://pytorch.org/tutorials/recipes/recipes/dynamic_quantization.html) to the UNet and VAE with the [torchao](../quantization/torchao) library. + +> [!TIP] +> Refer to our [torchao](../quantization/torchao) docs to learn more about how to use the Diffusers torchao integration. + +Configure the compiler tags for maximum speed. + +```py +import torch +from torchao import apply_dynamic_quant +from diffusers import StableDiffusionXLPipeline + +torch._inductor.config.conv_1x1_as_mm = True +torch._inductor.config.coordinate_descent_tuning = True +torch._inductor.config.epilogue_fusion = False +torch._inductor.config.coordinate_descent_check_all_directions = True +torch._inductor.config.force_fuse_int_mm_with_mul = True +torch._inductor.config.use_mixed_mm = True +``` + +Filter out some linear layers in the UNet and VAE which don't benefit from dynamic quantization with the [dynamic_quant_filter_fn](https://github.com/huggingface/diffusion-fast/blob/0f169640b1db106fe6a479f78c1ed3bfaeba3386/utils/pipeline_utils.py#L16). + +```py +pipeline = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.bfloat16 +).to("cuda") + +apply_dynamic_quant(pipeline.unet, dynamic_quant_filter_fn) +apply_dynamic_quant(pipeline.vae, dynamic_quant_filter_fn) + +prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k" +pipeline(prompt, num_inference_steps=30).images[0] +``` + +## Fused projection matrices + +> [!WARNING] +> The [fuse_qkv_projections](https://github.com/huggingface/diffusers/blob/58431f102cf39c3c8a569f32d71b2ea8caa461e1/src/diffusers/pipelines/pipeline_utils.py#L2034) method is experimental and support is limited to mostly Stable Diffusion pipelines. Take a look at this [PR](https://github.com/huggingface/diffusers/pull/6179) to learn more about how to enable it for other pipelines + +An input is projected into three subspaces, represented by the projection matrices Q, K, and V, in an attention block. These projections are typically calculated separately, but you can horizontally combine these into a single matrix and perform the projection in a single step. It increases the size of the matrix multiplications of the input projections and also improves the impact of quantization. + +```py +pipeline.fuse_qkv_projections() +``` \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/habana.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/habana.md new file mode 100644 index 0000000000000000000000000000000000000000..69964f3244654251c1671903e4ce3adb5bff581e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/habana.md @@ -0,0 +1,31 @@ + + +# Intel Gaudi + +The Intel Gaudi AI accelerator family includes [Intel Gaudi 1](https://habana.ai/products/gaudi/), [Intel Gaudi 2](https://habana.ai/products/gaudi2/), and [Intel Gaudi 3](https://habana.ai/products/gaudi3/). Each server is equipped with 8 devices, known as Habana Processing Units (HPUs), providing 128GB of memory on Gaudi 3, 96GB on Gaudi 2, and 32GB on the first-gen Gaudi. For more details on the underlying hardware architecture, check out the [Gaudi Architecture](https://docs.habana.ai/en/latest/Gaudi_Overview/Gaudi_Architecture.html) overview. + +Diffusers pipelines can take advantage of HPU acceleration, even if a pipeline hasn't been added to [Optimum for Intel Gaudi](https://huggingface.co/docs/optimum/main/en/habana/index) yet, with the [GPU Migration Toolkit](https://docs.habana.ai/en/latest/PyTorch/PyTorch_Model_Porting/GPU_Migration_Toolkit/GPU_Migration_Toolkit.html). + +Call `.to("hpu")` on your pipeline to move it to a HPU device as shown below for Flux: +```py +import torch +from diffusers import DiffusionPipeline + +pipeline = DiffusionPipeline.from_pretrained("black-forest-labs/FLUX.1-schnell", torch_dtype=torch.bfloat16) +pipeline.to("hpu") + +image = pipeline("An image of a squirrel in Picasso style").images[0] +``` + +> [!TIP] +> For Gaudi-optimized diffusion pipeline implementations, we recommend using [Optimum for Intel Gaudi](https://huggingface.co/docs/optimum/main/en/habana/index). diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/memory.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/memory.md new file mode 100644 index 0000000000000000000000000000000000000000..6b853a7a084b4ae3d8a60281be9808ab70120aac --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/memory.md @@ -0,0 +1,522 @@ + + +# Reduce memory usage + +Modern diffusion models like [Flux](../api/pipelines/flux) and [Wan](../api/pipelines/wan) have billions of parameters that take up a lot of memory on your hardware for inference. This is challenging because common GPUs often don't have sufficient memory. To overcome the memory limitations, you can use more than one GPU (if available), offload some of the pipeline components to the CPU, and more. + +This guide will show you how to reduce your memory usage. + +> [!TIP] +> Keep in mind these techniques may need to be adjusted depending on the model! For example, a transformer-based diffusion model may not benefit equally from these inference speed optimizations as a UNet-based model. + +## Multiple GPUs + +If you have access to more than one GPU, there a few options for efficiently loading and distributing a large model across your hardware. These features are supported by the [Accelerate](https://huggingface.co/docs/accelerate/index) library, so make sure it is installed first. + +```bash +pip install -U accelerate +``` + +### Sharded checkpoints + +Loading large checkpoints in several shards in useful because the shards are loaded one at a time. This keeps memory usage low, only requiring enough memory for the model size and the largest shard size. We recommend sharding when the fp32 checkpoint is greater than 5GB. The default shard size is 5GB. + +Shard a checkpoint in [`~DiffusionPipeline.save_pretrained`] with the `max_shard_size` parameter. + +```py +from diffusers import AutoModel + +unet = AutoModel.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", subfolder="unet" +) +unet.save_pretrained("sdxl-unet-sharded", max_shard_size="5GB") +``` + +Now you can use the sharded checkpoint, instead of the regular checkpoint, to save memory. + +```py +import torch +from diffusers import AutoModel, StableDiffusionXLPipeline + +unet = AutoModel.from_pretrained( + "username/sdxl-unet-sharded", torch_dtype=torch.float16 +) +pipeline = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", + unet=unet, + torch_dtype=torch.float16 +).to("cuda") +``` + +### Device placement + +> [!WARNING] +> Device placement is an experimental feature and the API may change. Only the `balanced` strategy is supported at the moment. We plan to support additional mapping strategies in the future. + +The `device_map` parameter controls how the model components in a pipeline are distributed across devices. The `balanced` device placement strategy evenly splits the pipeline across all available devices. + +```py +import torch +from diffusers import AutoModel, StableDiffusionXLPipeline + +pipeline = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", + torch_dtype=torch.float16, + device_map="balanced" +) +``` + +You can inspect a pipeline's device map with `hf_device_map`. + +```py +print(pipeline.hf_device_map) +{'unet': 1, 'vae': 1, 'safety_checker': 0, 'text_encoder': 0} +``` + +The `device_map` parameter also works on the model-level. This is useful for loading large models, such as the Flux diffusion transformer which has 12.5B parameters. Instead of `balanced`, set it to `"auto"` to automatically distribute a model across the fastest device first before moving to slower devices. Refer to the [Model sharding](../training/distributed_inference#model-sharding) docs for more details. + +```py +import torch +from diffusers import AutoModel + +transformer = AutoModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="transformer", + device_map="auto", + torch_dtype=torch.bfloat16 +) +``` + +For more fine-grained control, pass a dictionary to enforce the maximum GPU memory to use on each device. If a device is not in `max_memory`, it is ignored and pipeline components won't be distributed to it. + +```py +import torch +from diffusers import AutoModel, StableDiffusionXLPipeline + +max_memory = {0:"1GB", 1:"1GB"} +pipeline = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", + torch_dtype=torch.float16, + device_map="balanced", + max_memory=max_memory +) +``` + +Diffusers uses the maxmium memory of all devices by default, but if they don't fit on the GPUs, then you'll need to use a single GPU and offload to the CPU with the methods below. + +- [`~DiffusionPipeline.enable_model_cpu_offload`] only works on a single GPU but a very large model may not fit on it +- [`~DiffusionPipeline.enable_sequential_cpu_offload`] may work but it is extremely slow and also limited to a single GPU + +Use the [`~DiffusionPipeline.reset_device_map`] method to reset the `device_map`. This is necessary if you want to use methods like `.to()`, [`~DiffusionPipeline.enable_sequential_cpu_offload`], and [`~DiffusionPipeline.enable_model_cpu_offload`] on a pipeline that was device-mapped. + +```py +pipeline.reset_device_map() +``` + +## VAE slicing + +VAE slicing saves memory by splitting large batches of inputs into a single batch of data and separately processing them. This method works best when generating more than one image at a time. + +For example, if you're generating 4 images at once, decoding would increase peak activation memory by 4x. VAE slicing reduces this by only decoding 1 image at a time instead of all 4 images at once. + +Call [`~StableDiffusionPipeline.enable_vae_slicing`] to enable sliced VAE. You can expect a small increase in performance when decoding multi-image batches and no performance impact for single-image batches. + +```py +import torch +from diffusers import AutoModel, StableDiffusionXLPipeline + +pipeline = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", + torch_dtype=torch.float16, +).to("cuda") +pipeline.enable_vae_slicing() +pipeline(["An astronaut riding a horse on Mars"]*32).images[0] +print(f"Max memory reserved: {torch.cuda.max_memory_allocated() / 1024**3:.2f} GB") +``` + +> [!WARNING] +> [`AutoencoderKLWan`] and [`AsymmetricAutoencoderKL`] don't support slicing. + +## VAE tiling + +VAE tiling saves memory by dividing an image into smaller overlapping tiles instead of processing the entire image at once. This also reduces peak memory usage because the GPU is only processing a tile at a time. + +Call [`~StableDiffusionPipeline.enable_vae_tiling`] to enable VAE tiling. The generated image may have some tone variation from tile-to-tile because they're decoded separately, but there shouldn't be any obvious seams between the tiles. Tiling is disabled for resolutions lower than a pre-specified (but configurable) limit. For example, this limit is 512x512 for the VAE in [`StableDiffusionPipeline`]. + +```py +import torch +from diffusers import AutoPipelineForImage2Image +from diffusers.utils import load_image + +pipeline = AutoPipelineForImage2Image.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", torch_dtype=torch.float16 +).to("cuda") +pipeline.enable_vae_tiling() + +init_image = load_image("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/img2img-sdxl-init.png") +prompt = "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k" +pipeline(prompt, image=init_image, strength=0.5).images[0] +print(f"Max memory reserved: {torch.cuda.max_memory_allocated() / 1024**3:.2f} GB") +``` + +> [!WARNING] +> [`AutoencoderKLWan`] and [`AsymmetricAutoencoderKL`] don't support tiling. + +## CPU offloading + +CPU offloading selectively moves weights from the GPU to the CPU. When a component is required, it is transferred to the GPU and when it isn't required, it is moved to the CPU. This method works on submodules rather than whole models. It saves memory by avoiding storing the entire model on the GPU. + +CPU offloading dramatically reduces memory usage, but it is also **extremely slow** because submodules are passed back and forth multiple times between devices. It can often be impractical due to how slow it is. + +> [!WARNING] +> Don't move the pipeline to CUDA before calling [`~DiffusionPipeline.enable_sequential_cpu_offload`], otherwise the amount of memory saved is only minimal (refer to this [issue](https://github.com/huggingface/diffusers/issues/1934) for more details). This is a stateful operation that installs hooks on the model. + +Call [`~DiffusionPipeline.enable_sequential_cpu_offload`] to enable it on a pipeline. + +```py +import torch +from diffusers import DiffusionPipeline + +pipeline = DiffusionPipeline.from_pretrained( + "black-forest-labs/FLUX.1-schnell", torch_dtype=torch.bfloat16 +) +pipeline.enable_sequential_cpu_offload() + +pipeline( + prompt="An astronaut riding a horse on Mars", + guidance_scale=0., + height=768, + width=1360, + num_inference_steps=4, + max_sequence_length=256, +).images[0] +print(f"Max memory reserved: {torch.cuda.max_memory_allocated() / 1024**3:.2f} GB") +``` + +## Model offloading + +Model offloading moves entire models to the GPU instead of selectively moving *some* layers or model components. One of the main pipeline models, usually the text encoder, UNet, and VAE, is placed on the GPU while the other components are held on the CPU. Components like the UNet that run multiple times stays on the GPU until its completely finished and no longer needed. This eliminates the communication overhead of [CPU offloading](#cpu-offloading) and makes model offloading a faster alternative. The tradeoff is memory savings won't be as large. + +> [!WARNING] +> Keep in mind that if models are reused outside the pipeline after hookes have been installed (see [Removing Hooks](https://huggingface.co/docs/accelerate/en/package_reference/big_modeling#accelerate.hooks.remove_hook_from_module) for more details), you need to run the entire pipeline and models in the expected order to properly offload them. This is a stateful operation that installs hooks on the model. + +Call [`~DiffusionPipeline.enable_model_cpu_offload`] to enable it on a pipeline. + +```py +import torch +from diffusers import DiffusionPipeline + +pipeline = DiffusionPipeline.from_pretrained( + "black-forest-labs/FLUX.1-schnell", torch_dtype=torch.bfloat16 +) +pipline.enable_model_cpu_offload() + +pipeline( + prompt="An astronaut riding a horse on Mars", + guidance_scale=0., + height=768, + width=1360, + num_inference_steps=4, + max_sequence_length=256, +).images[0] +print(f"Max memory reserved: {torch.cuda.max_memory_allocated() / 1024**3:.2f} GB") +``` + +[`~DiffusionPipeline.enable_model_cpu_offload`] also helps when you're using the [`~StableDiffusionXLPipeline.encode_prompt`] method on its own to generate the text encoders hidden state. + +## Group offloading + +Group offloading moves groups of internal layers ([torch.nn.ModuleList](https://pytorch.org/docs/stable/generated/torch.nn.ModuleList.html) or [torch.nn.Sequential](https://pytorch.org/docs/stable/generated/torch.nn.Sequential.html)) to the CPU. It uses less memory than [model offloading](#model-offloading) and it is faster than [CPU offloading](#cpu-offloading) because it reduces communication overhead. + +> [!WARNING] +> Group offloading may not work with all models if the forward implementation contains weight-dependent device casting of inputs because it may clash with group offloading's device casting mechanism. + +Call [`~ModelMixin.enable_group_offload`] to enable it for standard Diffusers model components that inherit from [`ModelMixin`]. For other model components that don't inherit from [`ModelMixin`], such as a generic [torch.nn.Module](https://pytorch.org/docs/stable/generated/torch.nn.Module.html), use [`~hooks.apply_group_offloading`] instead. + +The `offload_type` parameter can be set to `block_level` or `leaf_level`. + +- `block_level` offloads groups of layers based on the `num_blocks_per_group` parameter. For example, if `num_blocks_per_group=2` on a model with 40 layers, 2 layers are onloaded and offloaded at a time (20 total onloads/offloads). This drastically reduces memory requirements. +- `leaf_level` offloads individual layers at the lowest level and is equivalent to [CPU offloading](#cpu-offloading). But it can be made faster if you use streams without giving up inference speed. + +```py +import torch +from diffusers import CogVideoXPipeline +from diffusers.hooks import apply_group_offloading +from diffusers.utils import export_to_video + +onload_device = torch.device("cuda") +offload_device = torch.device("cpu") +pipeline = CogVideoXPipeline.from_pretrained("THUDM/CogVideoX-5b", torch_dtype=torch.bfloat16) + +# Use the enable_group_offload method for Diffusers model implementations +pipeline.transformer.enable_group_offload(onload_device=onload_device, offload_device=offload_device, offload_type="leaf_level") +pipeline.vae.enable_group_offload(onload_device=onload_device, offload_type="leaf_level") + +# Use the apply_group_offloading method for other model components +apply_group_offloading(pipeline.text_encoder, onload_device=onload_device, offload_type="block_level", num_blocks_per_group=2) + +prompt = ( + "A panda, dressed in a small, red jacket and a tiny hat, sits on a wooden stool in a serene bamboo forest. " + "The panda's fluffy paws strum a miniature acoustic guitar, producing soft, melodic tunes. Nearby, a few other " + "pandas gather, watching curiously and some clapping in rhythm. Sunlight filters through the tall bamboo, " + "casting a gentle glow on the scene. The panda's face is expressive, showing concentration and joy as it plays. " + "The background includes a small, flowing stream and vibrant green foliage, enhancing the peaceful and magical " + "atmosphere of this unique musical performance." +) +video = pipeline(prompt=prompt, guidance_scale=6, num_inference_steps=50).frames[0] +print(f"Max memory reserved: {torch.cuda.max_memory_allocated() / 1024**3:.2f} GB") +export_to_video(video, "output.mp4", fps=8) +``` + +### CUDA stream + +The `use_stream` parameter can be activated for CUDA devices that support asynchronous data transfer streams to reduce overall execution time compared to [CPU offloading](#cpu-offloading). It overlaps data transfer and computation by using layer prefetching. The next layer to be executed is loaded onto the GPU while the current layer is still being executed. It can increase CPU memory significantly so ensure you have 2x the amount of memory as the model size. + +Set `record_stream=True` for more of a speedup at the cost of slightly increased memory usage. Refer to the [torch.Tensor.record_stream](https://pytorch.org/docs/stable/generated/torch.Tensor.record_stream.html) docs to learn more. + +> [!TIP] +> When `use_stream=True` on VAEs with tiling enabled, make sure to do a dummy forward pass (possible with dummy inputs as well) before inference to avoid device mismatch errors. This may not work on all implementations, so feel free to open an issue if you encounter any problems. + +If you're using `block_level` group offloading with `use_stream` enabled, the `num_blocks_per_group` parameter should be set to `1`, otherwise a warning will be raised. + +```py +pipeline.transformer.enable_group_offload(onload_device=onload_device, offload_device=offload_device, offload_type="leaf_level", use_stream=True, record_stream=True) +``` + +The `low_cpu_mem_usage` parameter can be set to `True` to reduce CPU memory usage when using streams during group offloading. It is best for `leaf_level` offloading and when CPU memory is bottlenecked. Memory is saved by creating pinned tensors on the fly instead of pre-pinning them. However, this may increase overall execution time. + + + +The offloading strategies can be combined with [quantization](../quantization/overview.md) to enable further memory savings. For image generation, combining [quantization and model offloading](#model-offloading) can often give the best trade-off between quality, speed, and memory. However, for video generation, as the models are more +compute-bound, [group-offloading](#group-offloading) tends to be better. Group offloading provides considerable benefits when weight transfers can be overlapped with computation (must use streams). When applying group offloading with quantization on image generation models at typical resolutions (1024x1024, for example), it is usually not possible to *fully* overlap weight transfers if the compute kernel finishes faster, making it communication bound between CPU/GPU (due to device synchronizations). + + + +## Layerwise casting + +Layerwise casting stores weights in a smaller data format (for example, `torch.float8_e4m3fn` and `torch.float8_e5m2`) to use less memory and upcasts those weights to a higher precision like `torch.float16` or `torch.bfloat16` for computation. Certain layers (normalization and modulation related weights) are skipped because storing them in fp8 can degrade generation quality. + +> [!WARNING] +> Layerwise casting may not work with all models if the forward implementation contains internal typecasting of weights. The current implementation of layerwise casting assumes the forward pass is independent of the weight precision and the input datatypes are always specified in `compute_dtype` (see [here](https://github.com/huggingface/transformers/blob/7f5077e53682ca855afc826162b204ebf809f1f9/src/transformers/models/t5/modeling_t5.py#L294-L299) for an incompatible implementation). +> +> Layerwise casting may also fail on custom modeling implementations with [PEFT](https://huggingface.co/docs/peft/index) layers. There are some checks available but they are not extensively tested or guaranteed to work in all cases. + +Call [`~ModelMixin.enable_layerwise_casting`] to set the storage and computation datatypes. + +```py +import torch +from diffusers import CogVideoXPipeline, CogVideoXTransformer3DModel +from diffusers.utils import export_to_video + +transformer = CogVideoXTransformer3DModel.from_pretrained( + "THUDM/CogVideoX-5b", + subfolder="transformer", + torch_dtype=torch.bfloat16 +) +transformer.enable_layerwise_casting(storage_dtype=torch.float8_e4m3fn, compute_dtype=torch.bfloat16) + +pipeline = CogVideoXPipeline.from_pretrained("THUDM/CogVideoX-5b", + transformer=transformer, + torch_dtype=torch.bfloat16 +).to("cuda") +prompt = ( + "A panda, dressed in a small, red jacket and a tiny hat, sits on a wooden stool in a serene bamboo forest. " + "The panda's fluffy paws strum a miniature acoustic guitar, producing soft, melodic tunes. Nearby, a few other " + "pandas gather, watching curiously and some clapping in rhythm. Sunlight filters through the tall bamboo, " + "casting a gentle glow on the scene. The panda's face is expressive, showing concentration and joy as it plays. " + "The background includes a small, flowing stream and vibrant green foliage, enhancing the peaceful and magical " + "atmosphere of this unique musical performance." +) +video = pipeline(prompt=prompt, guidance_scale=6, num_inference_steps=50).frames[0] +print(f"Max memory reserved: {torch.cuda.max_memory_allocated() / 1024**3:.2f} GB") +export_to_video(video, "output.mp4", fps=8) +``` + +The [`~hooks.apply_layerwise_casting`] method can also be used if you need more control and flexibility. It can be partially applied to model layers by calling it on specific internal modules. Use the `skip_modules_pattern` or `skip_modules_classes` parameters to specify modules to avoid, such as the normalization and modulation layers. + +```python +import torch +from diffusers import CogVideoXTransformer3DModel +from diffusers.hooks import apply_layerwise_casting + +transformer = CogVideoXTransformer3DModel.from_pretrained( + "THUDM/CogVideoX-5b", + subfolder="transformer", + torch_dtype=torch.bfloat16 +) + +# skip the normalization layer +apply_layerwise_casting( + transformer, + storage_dtype=torch.float8_e4m3fn, + compute_dtype=torch.bfloat16, + skip_modules_classes=["norm"], + non_blocking=True, +) +``` + +## torch.channels_last + +[torch.channels_last](https://pytorch.org/tutorials/intermediate/memory_format_tutorial.html) flips how tensors are stored from `(batch size, channels, height, width)` to `(batch size, heigh, width, channels)`. This aligns the tensors with how the hardware sequentially accesses the tensors stored in memory and avoids skipping around in memory to access the pixel values. + +Not all operators currently support the channels-last format and may result in worst performance, but it is still worth trying. + +```py +print(pipeline.unet.conv_out.state_dict()["weight"].stride()) # (2880, 9, 3, 1) +pipeline.unet.to(memory_format=torch.channels_last) # in-place operation +print( + pipeline.unet.conv_out.state_dict()["weight"].stride() +) # (2880, 1, 960, 320) having a stride of 1 for the 2nd dimension proves that it works +``` + +## torch.jit.trace + +[torch.jit.trace](https://pytorch.org/docs/stable/generated/torch.jit.trace.html) records the operations a model performs on a sample input and creates a new, optimized representation of the model based on the recorded execution path. During tracing, the model is optimized to reduce overhead from Python and dynamic control flows and operations are fused together for more efficiency. The returned executable or [ScriptFunction](https://pytorch.org/docs/stable/generated/torch.jit.ScriptFunction.html) can be compiled. + +```py +import time +import torch +from diffusers import StableDiffusionPipeline +import functools + +# torch disable grad +torch.set_grad_enabled(False) + +# set variables +n_experiments = 2 +unet_runs_per_experiment = 50 + +# load sample inputs +def generate_inputs(): + sample = torch.randn((2, 4, 64, 64), device="cuda", dtype=torch.float16) + timestep = torch.rand(1, device="cuda", dtype=torch.float16) * 999 + encoder_hidden_states = torch.randn((2, 77, 768), device="cuda", dtype=torch.float16) + return sample, timestep, encoder_hidden_states + + +pipeline = StableDiffusionPipeline.from_pretrained( + "stable-diffusion-v1-5/stable-diffusion-v1-5", + torch_dtype=torch.float16, + use_safetensors=True, +).to("cuda") +unet = pipeline.unet +unet.eval() +unet.to(memory_format=torch.channels_last) # use channels_last memory format +unet.forward = functools.partial(unet.forward, return_dict=False) # set return_dict=False as default + +# warmup +for _ in range(3): + with torch.inference_mode(): + inputs = generate_inputs() + orig_output = unet(*inputs) + +# trace +print("tracing..") +unet_traced = torch.jit.trace(unet, inputs) +unet_traced.eval() +print("done tracing") + +# warmup and optimize graph +for _ in range(5): + with torch.inference_mode(): + inputs = generate_inputs() + orig_output = unet_traced(*inputs) + +# benchmarking +with torch.inference_mode(): + for _ in range(n_experiments): + torch.cuda.synchronize() + start_time = time.time() + for _ in range(unet_runs_per_experiment): + orig_output = unet_traced(*inputs) + torch.cuda.synchronize() + print(f"unet traced inference took {time.time() - start_time:.2f} seconds") + for _ in range(n_experiments): + torch.cuda.synchronize() + start_time = time.time() + for _ in range(unet_runs_per_experiment): + orig_output = unet(*inputs) + torch.cuda.synchronize() + print(f"unet inference took {time.time() - start_time:.2f} seconds") + +# save the model +unet_traced.save("unet_traced.pt") +``` + +Replace the pipeline's UNet with the traced version. + +```py +import torch +from diffusers import StableDiffusionPipeline +from dataclasses import dataclass + +@dataclass +class UNet2DConditionOutput: + sample: torch.Tensor + +pipeline = StableDiffusionPipeline.from_pretrained( + "stable-diffusion-v1-5/stable-diffusion-v1-5", + torch_dtype=torch.float16, + use_safetensors=True, +).to("cuda") + +# use jitted unet +unet_traced = torch.jit.load("unet_traced.pt") + +# del pipeline.unet +class TracedUNet(torch.nn.Module): + def __init__(self): + super().__init__() + self.in_channels = pipe.unet.config.in_channels + self.device = pipe.unet.device + + def forward(self, latent_model_input, t, encoder_hidden_states): + sample = unet_traced(latent_model_input, t, encoder_hidden_states)[0] + return UNet2DConditionOutput(sample=sample) + +pipeline.unet = TracedUNet() + +with torch.inference_mode(): + image = pipe([prompt] * 1, num_inference_steps=50).images[0] +``` + +## Memory-efficient attention + +> [!TIP] +> Memory-efficient attention optimizes for memory usage *and* [inference speed](./fp16#scaled-dot-product-attention! + +The Transformers attention mechanism is memory-intensive, especially for long sequences, so you can try using different and more memory-efficient attention types. + +By default, if PyTorch >= 2.0 is installed, [scaled dot-product attention (SDPA)](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html) is used. You don't need to make any additional changes to your code. + +SDPA supports [FlashAttention](https://github.com/Dao-AILab/flash-attention) and [xFormers](https://github.com/facebookresearch/xformers) as well as a native C++ PyTorch implementation. It automatically selects the most optimal implementation based on your input. + +You can explicitly use xFormers with the [`~ModelMixin.enable_xformers_memory_efficient_attention`] method. + +```py +# pip install xformers +import torch +from diffusers import StableDiffusionXLPipeline + +pipeline = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", + torch_dtype=torch.float16, +).to("cuda") +pipeline.enable_xformers_memory_efficient_attention() +``` + +Call [`~ModelMixin.disable_xformers_memory_efficient_attention`] to disable it. + +```py +pipeline.disable_xformers_memory_efficient_attention() +``` \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/mps.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/mps.md new file mode 100644 index 0000000000000000000000000000000000000000..65fa95a2d1529dad7f0ba3571363c8b0e8be97c3 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/mps.md @@ -0,0 +1,85 @@ + + +# Metal Performance Shaders (MPS) + +> [!TIP] +> Pipelines with a MPS badge indicate a model can take advantage of the MPS backend on Apple silicon devices for faster inference. Feel free to open a [Pull Request](https://github.com/huggingface/diffusers/compare) to add this badge to pipelines that are missing it. + +🤗 Diffusers is compatible with Apple silicon (M1/M2 chips) using the PyTorch [`mps`](https://pytorch.org/docs/stable/notes/mps.html) device, which uses the Metal framework to leverage the GPU on MacOS devices. You'll need to have: + +- macOS computer with Apple silicon (M1/M2) hardware +- macOS 12.6 or later (13.0 or later recommended) +- arm64 version of Python +- [PyTorch 2.0](https://pytorch.org/get-started/locally/) (recommended) or 1.13 (minimum version supported for `mps`) + +The `mps` backend uses PyTorch's `.to()` interface to move the Stable Diffusion pipeline on to your M1 or M2 device: + +```python +from diffusers import DiffusionPipeline + +pipe = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5") +pipe = pipe.to("mps") + +# Recommended if your computer has < 64 GB of RAM +pipe.enable_attention_slicing() + +prompt = "a photo of an astronaut riding a horse on mars" +image = pipe(prompt).images[0] +image +``` + + + +The PyTorch [mps](https://pytorch.org/docs/stable/notes/mps.html) backend does not support NDArray sizes greater than `2**32`. Please open an [Issue](https://github.com/huggingface/diffusers/issues/new/choose) if you encounter this problem so we can investigate. + + + +If you're using **PyTorch 1.13**, you need to "prime" the pipeline with an additional one-time pass through it. This is a temporary workaround for an issue where the first inference pass produces slightly different results than subsequent ones. You only need to do this pass once, and after just one inference step you can discard the result. + +```diff + from diffusers import DiffusionPipeline + + pipe = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5").to("mps") + pipe.enable_attention_slicing() + + prompt = "a photo of an astronaut riding a horse on mars" + # First-time "warmup" pass if PyTorch version is 1.13 ++ _ = pipe(prompt, num_inference_steps=1) + + # Results match those from the CPU device after the warmup pass. + image = pipe(prompt).images[0] +``` + +## Troubleshoot + +This section lists some common issues with using the `mps` backend and how to solve them. + +### Attention slicing + +M1/M2 performance is very sensitive to memory pressure. When this occurs, the system automatically swaps if it needs to which significantly degrades performance. + +To prevent this from happening, we recommend *attention slicing* to reduce memory pressure during inference and prevent swapping. This is especially relevant if your computer has less than 64GB of system RAM, or if you generate images at non-standard resolutions larger than 512×512 pixels. Call the [`~DiffusionPipeline.enable_attention_slicing`] function on your pipeline: + +```py +from diffusers import DiffusionPipeline +import torch + +pipeline = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16, variant="fp16", use_safetensors=True).to("mps") +pipeline.enable_attention_slicing() +``` + +Attention slicing performs the costly attention operation in multiple steps instead of all at once. It usually improves performance by ~20% in computers without universal memory, but we've observed *better performance* in most Apple silicon computers unless you have 64GB of RAM or more. + +### Batch inference + +Generating multiple prompts in a batch can crash or fail to work reliably. If this is the case, try iterating instead of batching. \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/neuron.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/neuron.md new file mode 100644 index 0000000000000000000000000000000000000000..b10050e64d7f976451c84b734e8f537a75c888fe --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/neuron.md @@ -0,0 +1,61 @@ + + +# AWS Neuron + +Diffusers functionalities are available on [AWS Inf2 instances](https://aws.amazon.com/ec2/instance-types/inf2/), which are EC2 instances powered by [Neuron machine learning accelerators](https://aws.amazon.com/machine-learning/inferentia/). These instances aim to provide better compute performance (higher throughput, lower latency) with good cost-efficiency, making them good candidates for AWS users to deploy diffusion models to production. + +[Optimum Neuron](https://huggingface.co/docs/optimum-neuron/en/index) is the interface between Hugging Face libraries and AWS Accelerators, including AWS [Trainium](https://aws.amazon.com/machine-learning/trainium/) and AWS [Inferentia](https://aws.amazon.com/machine-learning/inferentia/). It supports many of the features in Diffusers with similar APIs, so it is easier to learn if you're already familiar with Diffusers. Once you have created an AWS Inf2 instance, install Optimum Neuron. + +```bash +python -m pip install --upgrade-strategy eager optimum[neuronx] +``` + + + +We provide pre-built [Hugging Face Neuron Deep Learning AMI](https://aws.amazon.com/marketplace/pp/prodview-gr3e6yiscria2) (DLAMI) and Optimum Neuron containers for Amazon SageMaker. It's recommended to correctly set up your environment. + + + +The example below demonstrates how to generate images with the Stable Diffusion XL model on an inf2.8xlarge instance (you can switch to cheaper inf2.xlarge instances once the model is compiled). To generate some images, use the [`~optimum.neuron.NeuronStableDiffusionXLPipeline`] class, which is similar to the [`StableDiffusionXLPipeline`] class in Diffusers. + +Unlike Diffusers, you need to compile models in the pipeline to the Neuron format, `.neuron`. Launch the following command to export the model to the `.neuron` format. + +```bash +optimum-cli export neuron --model stabilityai/stable-diffusion-xl-base-1.0 \ + --batch_size 1 \ + --height 1024 `# height in pixels of generated image, eg. 768, 1024` \ + --width 1024 `# width in pixels of generated image, eg. 768, 1024` \ + --num_images_per_prompt 1 `# number of images to generate per prompt, defaults to 1` \ + --auto_cast matmul `# cast only matrix multiplication operations` \ + --auto_cast_type bf16 `# cast operations from FP32 to BF16` \ + sd_neuron_xl/ +``` + +Now generate some images with the pre-compiled SDXL model. + +```python +>>> from optimum.neuron import NeuronStableDiffusionXLPipeline + +>>> stable_diffusion_xl = NeuronStableDiffusionXLPipeline.from_pretrained("sd_neuron_xl/") +>>> prompt = "a pig with wings flying in floating US dollar banknotes in the air, skyscrapers behind, warm color palette, muted colors, detailed, 8k" +>>> image = stable_diffusion_xl(prompt).images[0] +``` + +peggy generated by sdxl on inf2 + +Feel free to check out more guides and examples on different use cases from the Optimum Neuron [documentation](https://huggingface.co/docs/optimum-neuron/en/inference_tutorials/stable_diffusion#generate-images-with-stable-diffusion-models-on-aws-inferentia)! diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/onnx.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/onnx.md new file mode 100644 index 0000000000000000000000000000000000000000..84c0d0c263e51866fbc2fffb74d26b30753cea89 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/onnx.md @@ -0,0 +1,86 @@ + + +# ONNX Runtime + +🤗 [Optimum](https://github.com/huggingface/optimum) provides a Stable Diffusion pipeline compatible with ONNX Runtime. You'll need to install 🤗 Optimum with the following command for ONNX Runtime support: + +```bash +pip install -q optimum["onnxruntime"] +``` + +This guide will show you how to use the Stable Diffusion and Stable Diffusion XL (SDXL) pipelines with ONNX Runtime. + +## Stable Diffusion + +To load and run inference, use the [`~optimum.onnxruntime.ORTStableDiffusionPipeline`]. If you want to load a PyTorch model and convert it to the ONNX format on-the-fly, set `export=True`: + +```python +from optimum.onnxruntime import ORTStableDiffusionPipeline + +model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5" +pipeline = ORTStableDiffusionPipeline.from_pretrained(model_id, export=True) +prompt = "sailing ship in storm by Leonardo da Vinci" +image = pipeline(prompt).images[0] +pipeline.save_pretrained("./onnx-stable-diffusion-v1-5") +``` + + + +Generating multiple prompts in a batch seems to take too much memory. While we look into it, you may need to iterate instead of batching. + + + +To export the pipeline in the ONNX format offline and use it later for inference, +use the [`optimum-cli export`](https://huggingface.co/docs/optimum/main/en/exporters/onnx/usage_guides/export_a_model#exporting-a-model-to-onnx-using-the-cli) command: + +```bash +optimum-cli export onnx --model stable-diffusion-v1-5/stable-diffusion-v1-5 sd_v15_onnx/ +``` + +Then to perform inference (you don't have to specify `export=True` again): + +```python +from optimum.onnxruntime import ORTStableDiffusionPipeline + +model_id = "sd_v15_onnx" +pipeline = ORTStableDiffusionPipeline.from_pretrained(model_id) +prompt = "sailing ship in storm by Leonardo da Vinci" +image = pipeline(prompt).images[0] +``` + +
+ +
+ +You can find more examples in 🤗 Optimum [documentation](https://huggingface.co/docs/optimum/), and Stable Diffusion is supported for text-to-image, image-to-image, and inpainting. + +## Stable Diffusion XL + +To load and run inference with SDXL, use the [`~optimum.onnxruntime.ORTStableDiffusionXLPipeline`]: + +```python +from optimum.onnxruntime import ORTStableDiffusionXLPipeline + +model_id = "stabilityai/stable-diffusion-xl-base-1.0" +pipeline = ORTStableDiffusionXLPipeline.from_pretrained(model_id) +prompt = "sailing ship in storm by Leonardo da Vinci" +image = pipeline(prompt).images[0] +``` + +To export the pipeline in the ONNX format and use it later for inference, use the [`optimum-cli export`](https://huggingface.co/docs/optimum/main/en/exporters/onnx/usage_guides/export_a_model#exporting-a-model-to-onnx-using-the-cli) command: + +```bash +optimum-cli export onnx --model stabilityai/stable-diffusion-xl-base-1.0 --task stable-diffusion-xl sd_xl_onnx/ +``` + +SDXL in the ONNX format is supported for text-to-image and image-to-image. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/open_vino.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/open_vino.md new file mode 100644 index 0000000000000000000000000000000000000000..b2af9d9d62e14d22d703a11ac7f47e878677c829 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/open_vino.md @@ -0,0 +1,80 @@ + + +# OpenVINO + +🤗 [Optimum](https://github.com/huggingface/optimum-intel) provides Stable Diffusion pipelines compatible with OpenVINO to perform inference on a variety of Intel processors (see the [full list](https://docs.openvino.ai/latest/openvino_docs_OV_UG_supported_plugins_Supported_Devices.html) of supported devices). + +You'll need to install 🤗 Optimum Intel with the `--upgrade-strategy eager` option to ensure [`optimum-intel`](https://github.com/huggingface/optimum-intel) is using the latest version: + +```bash +pip install --upgrade-strategy eager optimum["openvino"] +``` + +This guide will show you how to use the Stable Diffusion and Stable Diffusion XL (SDXL) pipelines with OpenVINO. + +## Stable Diffusion + +To load and run inference, use the [`~optimum.intel.OVStableDiffusionPipeline`]. If you want to load a PyTorch model and convert it to the OpenVINO format on-the-fly, set `export=True`: + +```python +from optimum.intel import OVStableDiffusionPipeline + +model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5" +pipeline = OVStableDiffusionPipeline.from_pretrained(model_id, export=True) +prompt = "sailing ship in storm by Rembrandt" +image = pipeline(prompt).images[0] + +# Don't forget to save the exported model +pipeline.save_pretrained("openvino-sd-v1-5") +``` + +To further speed-up inference, statically reshape the model. If you change any parameters such as the outputs height or width, you’ll need to statically reshape your model again. + +```python +# Define the shapes related to the inputs and desired outputs +batch_size, num_images, height, width = 1, 1, 512, 512 + +# Statically reshape the model +pipeline.reshape(batch_size, height, width, num_images) +# Compile the model before inference +pipeline.compile() + +image = pipeline( + prompt, + height=height, + width=width, + num_images_per_prompt=num_images, +).images[0] +``` +
+ +
+ +You can find more examples in the 🤗 Optimum [documentation](https://huggingface.co/docs/optimum/intel/inference#stable-diffusion), and Stable Diffusion is supported for text-to-image, image-to-image, and inpainting. + +## Stable Diffusion XL + +To load and run inference with SDXL, use the [`~optimum.intel.OVStableDiffusionXLPipeline`]: + +```python +from optimum.intel import OVStableDiffusionXLPipeline + +model_id = "stabilityai/stable-diffusion-xl-base-1.0" +pipeline = OVStableDiffusionXLPipeline.from_pretrained(model_id) +prompt = "sailing ship in storm by Rembrandt" +image = pipeline(prompt).images[0] +``` + +To further speed-up inference, [statically reshape](#stable-diffusion) the model as shown in the Stable Diffusion section. + +You can find more examples in the 🤗 Optimum [documentation](https://huggingface.co/docs/optimum/intel/inference#stable-diffusion-xl), and running SDXL in OpenVINO is supported for text-to-image and image-to-image. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/para_attn.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/para_attn.md new file mode 100644 index 0000000000000000000000000000000000000000..94b0d5ce3af4c570fef6806df306a2bbb3c15d00 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/para_attn.md @@ -0,0 +1,497 @@ +# ParaAttention + +
+ +
+
+ +
+ + +Large image and video generation models, such as [FLUX.1-dev](https://huggingface.co/black-forest-labs/FLUX.1-dev) and [HunyuanVideo](https://huggingface.co/tencent/HunyuanVideo), can be an inference challenge for real-time applications and deployment because of their size. + +[ParaAttention](https://github.com/chengzeyi/ParaAttention) is a library that implements **context parallelism** and **first block cache**, and can be combined with other techniques (torch.compile, fp8 dynamic quantization), to accelerate inference. + +This guide will show you how to apply ParaAttention to FLUX.1-dev and HunyuanVideo on NVIDIA L20 GPUs. +No optimizations are applied for our baseline benchmark, except for HunyuanVideo to avoid out-of-memory errors. + +Our baseline benchmark shows that FLUX.1-dev is able to generate a 1024x1024 resolution image in 28 steps in 26.36 seconds, and HunyuanVideo is able to generate 129 frames at 720p resolution in 30 steps in 3675.71 seconds. + +> [!TIP] +> For even faster inference with context parallelism, try using NVIDIA A100 or H100 GPUs (if available) with NVLink support, especially when there is a large number of GPUs. + +## First Block Cache + +Caching the output of the transformers blocks in the model and reusing them in the next inference steps reduces the computation cost and makes inference faster. + +However, it is hard to decide when to reuse the cache to ensure quality generated images or videos. ParaAttention directly uses the **residual difference of the first transformer block output** to approximate the difference among model outputs. When the difference is small enough, the residual difference of previous inference steps is reused. In other words, the denoising step is skipped. + +This achieves a 2x speedup on FLUX.1-dev and HunyuanVideo inference with very good quality. + +
+ Cache in Diffusion Transformer +
How AdaCache works, First Block Cache is a variant of it
+
+ + + + +To apply first block cache on FLUX.1-dev, call `apply_cache_on_pipe` as shown below. 0.08 is the default residual difference value for FLUX models. + +```python +import time +import torch +from diffusers import FluxPipeline + +pipe = FluxPipeline.from_pretrained( + "black-forest-labs/FLUX.1-dev", + torch_dtype=torch.bfloat16, +).to("cuda") + +from para_attn.first_block_cache.diffusers_adapters import apply_cache_on_pipe + +apply_cache_on_pipe(pipe, residual_diff_threshold=0.08) + +# Enable memory savings +# pipe.enable_model_cpu_offload() +# pipe.enable_sequential_cpu_offload() + +begin = time.time() +image = pipe( + "A cat holding a sign that says hello world", + num_inference_steps=28, +).images[0] +end = time.time() +print(f"Time: {end - begin:.2f}s") + +print("Saving image to flux.png") +image.save("flux.png") +``` + +| Optimizations | Original | FBCache rdt=0.06 | FBCache rdt=0.08 | FBCache rdt=0.10 | FBCache rdt=0.12 | +| - | - | - | - | - | - | +| Preview | ![Original](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/para-attn/flux-original.png) | ![FBCache rdt=0.06](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/para-attn/flux-fbc-0.06.png) | ![FBCache rdt=0.08](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/para-attn/flux-fbc-0.08.png) | ![FBCache rdt=0.10](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/para-attn/flux-fbc-0.10.png) | ![FBCache rdt=0.12](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/para-attn/flux-fbc-0.12.png) | +| Wall Time (s) | 26.36 | 21.83 | 17.01 | 16.00 | 13.78 | + +First Block Cache reduced the inference speed to 17.01 seconds compared to the baseline, or 1.55x faster, while maintaining nearly zero quality loss. + + + + +To apply First Block Cache on HunyuanVideo, `apply_cache_on_pipe` as shown below. 0.06 is the default residual difference value for HunyuanVideo models. + +```python +import time +import torch +from diffusers import HunyuanVideoPipeline, HunyuanVideoTransformer3DModel +from diffusers.utils import export_to_video + +model_id = "tencent/HunyuanVideo" +transformer = HunyuanVideoTransformer3DModel.from_pretrained( + model_id, + subfolder="transformer", + torch_dtype=torch.bfloat16, + revision="refs/pr/18", +) +pipe = HunyuanVideoPipeline.from_pretrained( + model_id, + transformer=transformer, + torch_dtype=torch.float16, + revision="refs/pr/18", +).to("cuda") + +from para_attn.first_block_cache.diffusers_adapters import apply_cache_on_pipe + +apply_cache_on_pipe(pipe, residual_diff_threshold=0.6) + +pipe.vae.enable_tiling() + +begin = time.time() +output = pipe( + prompt="A cat walks on the grass, realistic", + height=720, + width=1280, + num_frames=129, + num_inference_steps=30, +).frames[0] +end = time.time() +print(f"Time: {end - begin:.2f}s") + +print("Saving video to hunyuan_video.mp4") +export_to_video(output, "hunyuan_video.mp4", fps=15) +``` + + + + HunyuanVideo without FBCache + + + + HunyuanVideo with FBCache + +First Block Cache reduced the inference speed to 2271.06 seconds compared to the baseline, or 1.62x faster, while maintaining nearly zero quality loss. + + + + +## fp8 quantization + +fp8 with dynamic quantization further speeds up inference and reduces memory usage. Both the activations and weights must be quantized in order to use the 8-bit [NVIDIA Tensor Cores](https://www.nvidia.com/en-us/data-center/tensor-cores/). + +Use `float8_weight_only` and `float8_dynamic_activation_float8_weight` to quantize the text encoder and transformer model. + +The default quantization method is per tensor quantization, but if your GPU supports row-wise quantization, you can also try it for better accuracy. + +Install [torchao](https://github.com/pytorch/ao/tree/main) with the command below. + +```bash +pip3 install -U torch torchao +``` + +[torch.compile](https://pytorch.org/tutorials/intermediate/torch_compile_tutorial.html) with `mode="max-autotune-no-cudagraphs"` or `mode="max-autotune"` selects the best kernel for performance. Compilation can take a long time if it's the first time the model is called, but it is worth it once the model has been compiled. + +This example only quantizes the transformer model, but you can also quantize the text encoder to reduce memory usage even more. + +> [!TIP] +> Dynamic quantization can significantly change the distribution of the model output, so you need to change the `residual_diff_threshold` to a larger value for it to take effect. + + + + +```python +import time +import torch +from diffusers import FluxPipeline + +pipe = FluxPipeline.from_pretrained( + "black-forest-labs/FLUX.1-dev", + torch_dtype=torch.bfloat16, +).to("cuda") + +from para_attn.first_block_cache.diffusers_adapters import apply_cache_on_pipe + +apply_cache_on_pipe( + pipe, + residual_diff_threshold=0.12, # Use a larger value to make the cache take effect +) + +from torchao.quantization import quantize_, float8_dynamic_activation_float8_weight, float8_weight_only + +quantize_(pipe.text_encoder, float8_weight_only()) +quantize_(pipe.transformer, float8_dynamic_activation_float8_weight()) +pipe.transformer = torch.compile( + pipe.transformer, mode="max-autotune-no-cudagraphs", +) + +# Enable memory savings +# pipe.enable_model_cpu_offload() +# pipe.enable_sequential_cpu_offload() + +for i in range(2): + begin = time.time() + image = pipe( + "A cat holding a sign that says hello world", + num_inference_steps=28, + ).images[0] + end = time.time() + if i == 0: + print(f"Warm up time: {end - begin:.2f}s") + else: + print(f"Time: {end - begin:.2f}s") + +print("Saving image to flux.png") +image.save("flux.png") +``` + +fp8 dynamic quantization and torch.compile reduced the inference speed to 7.56 seconds compared to the baseline, or 3.48x faster. + + + + +```python +import time +import torch +from diffusers import HunyuanVideoPipeline, HunyuanVideoTransformer3DModel +from diffusers.utils import export_to_video + +model_id = "tencent/HunyuanVideo" +transformer = HunyuanVideoTransformer3DModel.from_pretrained( + model_id, + subfolder="transformer", + torch_dtype=torch.bfloat16, + revision="refs/pr/18", +) +pipe = HunyuanVideoPipeline.from_pretrained( + model_id, + transformer=transformer, + torch_dtype=torch.float16, + revision="refs/pr/18", +).to("cuda") + +from para_attn.first_block_cache.diffusers_adapters import apply_cache_on_pipe + +apply_cache_on_pipe(pipe) + +from torchao.quantization import quantize_, float8_dynamic_activation_float8_weight, float8_weight_only + +quantize_(pipe.text_encoder, float8_weight_only()) +quantize_(pipe.transformer, float8_dynamic_activation_float8_weight()) +pipe.transformer = torch.compile( + pipe.transformer, mode="max-autotune-no-cudagraphs", +) + +# Enable memory savings +pipe.vae.enable_tiling() +# pipe.enable_model_cpu_offload() +# pipe.enable_sequential_cpu_offload() + +for i in range(2): + begin = time.time() + output = pipe( + prompt="A cat walks on the grass, realistic", + height=720, + width=1280, + num_frames=129, + num_inference_steps=1 if i == 0 else 30, + ).frames[0] + end = time.time() + if i == 0: + print(f"Warm up time: {end - begin:.2f}s") + else: + print(f"Time: {end - begin:.2f}s") + +print("Saving video to hunyuan_video.mp4") +export_to_video(output, "hunyuan_video.mp4", fps=15) +``` + +A NVIDIA L20 GPU only has 48GB memory and could face out-of-memory (OOM) errors after compilation and if `enable_model_cpu_offload` isn't called because HunyuanVideo has very large activation tensors when running with high resolution and large number of frames. For GPUs with less than 80GB of memory, you can try reducing the resolution and number of frames to avoid OOM errors. + +Large video generation models are usually bottlenecked by the attention computations rather than the fully connected layers. These models don't significantly benefit from quantization and torch.compile. + + + + +## Context Parallelism + +Context Parallelism parallelizes inference and scales with multiple GPUs. The ParaAttention compositional design allows you to combine Context Parallelism with First Block Cache and dynamic quantization. + +> [!TIP] +> Refer to the [ParaAttention](https://github.com/chengzeyi/ParaAttention/tree/main) repository for detailed instructions and examples of how to scale inference with multiple GPUs. + +If the inference process needs to be persistent and serviceable, it is suggested to use [torch.multiprocessing](https://pytorch.org/docs/stable/multiprocessing.html) to write your own inference processor. This can eliminate the overhead of launching the process and loading and recompiling the model. + + + + +The code sample below combines First Block Cache, fp8 dynamic quantization, torch.compile, and Context Parallelism for the fastest inference speed. + +```python +import time +import torch +import torch.distributed as dist +from diffusers import FluxPipeline + +dist.init_process_group() + +torch.cuda.set_device(dist.get_rank()) + +pipe = FluxPipeline.from_pretrained( + "black-forest-labs/FLUX.1-dev", + torch_dtype=torch.bfloat16, +).to("cuda") + +from para_attn.context_parallel import init_context_parallel_mesh +from para_attn.context_parallel.diffusers_adapters import parallelize_pipe +from para_attn.parallel_vae.diffusers_adapters import parallelize_vae + +mesh = init_context_parallel_mesh( + pipe.device.type, + max_ring_dim_size=2, +) +parallelize_pipe( + pipe, + mesh=mesh, +) +parallelize_vae(pipe.vae, mesh=mesh._flatten()) + +from para_attn.first_block_cache.diffusers_adapters import apply_cache_on_pipe + +apply_cache_on_pipe( + pipe, + residual_diff_threshold=0.12, # Use a larger value to make the cache take effect +) + +from torchao.quantization import quantize_, float8_dynamic_activation_float8_weight, float8_weight_only + +quantize_(pipe.text_encoder, float8_weight_only()) +quantize_(pipe.transformer, float8_dynamic_activation_float8_weight()) +torch._inductor.config.reorder_for_compute_comm_overlap = True +pipe.transformer = torch.compile( + pipe.transformer, mode="max-autotune-no-cudagraphs", +) + +# Enable memory savings +# pipe.enable_model_cpu_offload(gpu_id=dist.get_rank()) +# pipe.enable_sequential_cpu_offload(gpu_id=dist.get_rank()) + +for i in range(2): + begin = time.time() + image = pipe( + "A cat holding a sign that says hello world", + num_inference_steps=28, + output_type="pil" if dist.get_rank() == 0 else "pt", + ).images[0] + end = time.time() + if dist.get_rank() == 0: + if i == 0: + print(f"Warm up time: {end - begin:.2f}s") + else: + print(f"Time: {end - begin:.2f}s") + +if dist.get_rank() == 0: + print("Saving image to flux.png") + image.save("flux.png") + +dist.destroy_process_group() +``` + +Save to `run_flux.py` and launch it with [torchrun](https://pytorch.org/docs/stable/elastic/run.html). + +```bash +# Use --nproc_per_node to specify the number of GPUs +torchrun --nproc_per_node=2 run_flux.py +``` + +Inference speed is reduced to 8.20 seconds compared to the baseline, or 3.21x faster, with 2 NVIDIA L20 GPUs. On 4 L20s, inference speed is 3.90 seconds, or 6.75x faster. + + + + +The code sample below combines First Block Cache and Context Parallelism for the fastest inference speed. + +```python +import time +import torch +import torch.distributed as dist +from diffusers import HunyuanVideoPipeline, HunyuanVideoTransformer3DModel +from diffusers.utils import export_to_video + +dist.init_process_group() + +torch.cuda.set_device(dist.get_rank()) + +model_id = "tencent/HunyuanVideo" +transformer = HunyuanVideoTransformer3DModel.from_pretrained( + model_id, + subfolder="transformer", + torch_dtype=torch.bfloat16, + revision="refs/pr/18", +) +pipe = HunyuanVideoPipeline.from_pretrained( + model_id, + transformer=transformer, + torch_dtype=torch.float16, + revision="refs/pr/18", +).to("cuda") + +from para_attn.context_parallel import init_context_parallel_mesh +from para_attn.context_parallel.diffusers_adapters import parallelize_pipe +from para_attn.parallel_vae.diffusers_adapters import parallelize_vae + +mesh = init_context_parallel_mesh( + pipe.device.type, +) +parallelize_pipe( + pipe, + mesh=mesh, +) +parallelize_vae(pipe.vae, mesh=mesh._flatten()) + +from para_attn.first_block_cache.diffusers_adapters import apply_cache_on_pipe + +apply_cache_on_pipe(pipe) + +# from torchao.quantization import quantize_, float8_dynamic_activation_float8_weight, float8_weight_only +# +# torch._inductor.config.reorder_for_compute_comm_overlap = True +# +# quantize_(pipe.text_encoder, float8_weight_only()) +# quantize_(pipe.transformer, float8_dynamic_activation_float8_weight()) +# pipe.transformer = torch.compile( +# pipe.transformer, mode="max-autotune-no-cudagraphs", +# ) + +# Enable memory savings +pipe.vae.enable_tiling() +# pipe.enable_model_cpu_offload(gpu_id=dist.get_rank()) +# pipe.enable_sequential_cpu_offload(gpu_id=dist.get_rank()) + +for i in range(2): + begin = time.time() + output = pipe( + prompt="A cat walks on the grass, realistic", + height=720, + width=1280, + num_frames=129, + num_inference_steps=1 if i == 0 else 30, + output_type="pil" if dist.get_rank() == 0 else "pt", + ).frames[0] + end = time.time() + if dist.get_rank() == 0: + if i == 0: + print(f"Warm up time: {end - begin:.2f}s") + else: + print(f"Time: {end - begin:.2f}s") + +if dist.get_rank() == 0: + print("Saving video to hunyuan_video.mp4") + export_to_video(output, "hunyuan_video.mp4", fps=15) + +dist.destroy_process_group() +``` + +Save to `run_hunyuan_video.py` and launch it with [torchrun](https://pytorch.org/docs/stable/elastic/run.html). + +```bash +# Use --nproc_per_node to specify the number of GPUs +torchrun --nproc_per_node=8 run_hunyuan_video.py +``` + +Inference speed is reduced to 649.23 seconds compared to the baseline, or 5.66x faster, with 8 NVIDIA L20 GPUs. + + + + +## Benchmarks + + + + +| GPU Type | Number of GPUs | Optimizations | Wall Time (s) | Speedup | +| - | - | - | - | - | +| NVIDIA L20 | 1 | Baseline | 26.36 | 1.00x | +| NVIDIA L20 | 1 | FBCache (rdt=0.08) | 17.01 | 1.55x | +| NVIDIA L20 | 1 | FP8 DQ | 13.40 | 1.96x | +| NVIDIA L20 | 1 | FBCache (rdt=0.12) + FP8 DQ | 7.56 | 3.48x | +| NVIDIA L20 | 2 | FBCache (rdt=0.12) + FP8 DQ + CP | 4.92 | 5.35x | +| NVIDIA L20 | 4 | FBCache (rdt=0.12) + FP8 DQ + CP | 3.90 | 6.75x | + + + + +| GPU Type | Number of GPUs | Optimizations | Wall Time (s) | Speedup | +| - | - | - | - | - | +| NVIDIA L20 | 1 | Baseline | 3675.71 | 1.00x | +| NVIDIA L20 | 1 | FBCache | 2271.06 | 1.62x | +| NVIDIA L20 | 2 | FBCache + CP | 1132.90 | 3.24x | +| NVIDIA L20 | 4 | FBCache + CP | 718.15 | 5.12x | +| NVIDIA L20 | 8 | FBCache + CP | 649.23 | 5.66x | + + + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/tgate.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/tgate.md new file mode 100644 index 0000000000000000000000000000000000000000..90e0bc32f71b085244ce60b43bb7538c767724ef --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/tgate.md @@ -0,0 +1,182 @@ +# T-GATE + +[T-GATE](https://github.com/HaozheLiu-ST/T-GATE/tree/main) accelerates inference for [Stable Diffusion](../api/pipelines/stable_diffusion/overview), [PixArt](../api/pipelines/pixart), and [Latency Consistency Model](../api/pipelines/latent_consistency_models.md) pipelines by skipping the cross-attention calculation once it converges. This method doesn't require any additional training and it can speed up inference from 10-50%. T-GATE is also compatible with other optimization methods like [DeepCache](./deepcache). + +Before you begin, make sure you install T-GATE. + +```bash +pip install tgate +pip install -U torch diffusers transformers accelerate DeepCache +``` + + +To use T-GATE with a pipeline, you need to use its corresponding loader. + +| Pipeline | T-GATE Loader | +|---|---| +| PixArt | TgatePixArtLoader | +| Stable Diffusion XL | TgateSDXLLoader | +| Stable Diffusion XL + DeepCache | TgateSDXLDeepCacheLoader | +| Stable Diffusion | TgateSDLoader | +| Stable Diffusion + DeepCache | TgateSDDeepCacheLoader | + +Next, create a `TgateLoader` with a pipeline, the gate step (the time step to stop calculating the cross attention), and the number of inference steps. Then call the `tgate` method on the pipeline with a prompt, gate step, and the number of inference steps. + +Let's see how to enable this for several different pipelines. + + + + +Accelerate `PixArtAlphaPipeline` with T-GATE: + +```py +import torch +from diffusers import PixArtAlphaPipeline +from tgate import TgatePixArtLoader + +pipe = PixArtAlphaPipeline.from_pretrained("PixArt-alpha/PixArt-XL-2-1024-MS", torch_dtype=torch.float16) + +gate_step = 8 +inference_step = 25 +pipe = TgatePixArtLoader( + pipe, + gate_step=gate_step, + num_inference_steps=inference_step, +).to("cuda") + +image = pipe.tgate( + "An alpaca made of colorful building blocks, cyberpunk.", + gate_step=gate_step, + num_inference_steps=inference_step, +).images[0] +``` + + + +Accelerate `StableDiffusionXLPipeline` with T-GATE: + +```py +import torch +from diffusers import StableDiffusionXLPipeline +from diffusers import DPMSolverMultistepScheduler +from tgate import TgateSDXLLoader + +pipe = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", + torch_dtype=torch.float16, + variant="fp16", + use_safetensors=True, +) +pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config) + +gate_step = 10 +inference_step = 25 +pipe = TgateSDXLLoader( + pipe, + gate_step=gate_step, + num_inference_steps=inference_step, +).to("cuda") + +image = pipe.tgate( + "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k.", + gate_step=gate_step, + num_inference_steps=inference_step +).images[0] +``` + + + +Accelerate `StableDiffusionXLPipeline` with [DeepCache](https://github.com/horseee/DeepCache) and T-GATE: + +```py +import torch +from diffusers import StableDiffusionXLPipeline +from diffusers import DPMSolverMultistepScheduler +from tgate import TgateSDXLDeepCacheLoader + +pipe = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", + torch_dtype=torch.float16, + variant="fp16", + use_safetensors=True, +) +pipe.scheduler = DPMSolverMultistepScheduler.from_config(pipe.scheduler.config) + +gate_step = 10 +inference_step = 25 +pipe = TgateSDXLDeepCacheLoader( + pipe, + cache_interval=3, + cache_branch_id=0, +).to("cuda") + +image = pipe.tgate( + "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k.", + gate_step=gate_step, + num_inference_steps=inference_step +).images[0] +``` + + + +Accelerate `latent-consistency/lcm-sdxl` with T-GATE: + +```py +import torch +from diffusers import StableDiffusionXLPipeline +from diffusers import UNet2DConditionModel, LCMScheduler +from diffusers import DPMSolverMultistepScheduler +from tgate import TgateSDXLLoader + +unet = UNet2DConditionModel.from_pretrained( + "latent-consistency/lcm-sdxl", + torch_dtype=torch.float16, + variant="fp16", +) +pipe = StableDiffusionXLPipeline.from_pretrained( + "stabilityai/stable-diffusion-xl-base-1.0", + unet=unet, + torch_dtype=torch.float16, + variant="fp16", +) +pipe.scheduler = LCMScheduler.from_config(pipe.scheduler.config) + +gate_step = 1 +inference_step = 4 +pipe = TgateSDXLLoader( + pipe, + gate_step=gate_step, + num_inference_steps=inference_step, + lcm=True +).to("cuda") + +image = pipe.tgate( + "Astronaut in a jungle, cold color palette, muted colors, detailed, 8k.", + gate_step=gate_step, + num_inference_steps=inference_step +).images[0] +``` + + + +T-GATE also supports [`StableDiffusionPipeline`] and [PixArt-alpha/PixArt-LCM-XL-2-1024-MS](https://hf.co/PixArt-alpha/PixArt-LCM-XL-2-1024-MS). + +## Benchmarks +| Model | MACs | Param | Latency | Zero-shot 10K-FID on MS-COCO | +|-----------------------|----------|-----------|---------|---------------------------| +| SD-1.5 | 16.938T | 859.520M | 7.032s | 23.927 | +| SD-1.5 w/ T-GATE | 9.875T | 815.557M | 4.313s | 20.789 | +| SD-2.1 | 38.041T | 865.785M | 16.121s | 22.609 | +| SD-2.1 w/ T-GATE | 22.208T | 815.433 M | 9.878s | 19.940 | +| SD-XL | 149.438T | 2.570B | 53.187s | 24.628 | +| SD-XL w/ T-GATE | 84.438T | 2.024B | 27.932s | 22.738 | +| Pixart-Alpha | 107.031T | 611.350M | 61.502s | 38.669 | +| Pixart-Alpha w/ T-GATE | 65.318T | 462.585M | 37.867s | 35.825 | +| DeepCache (SD-XL) | 57.888T | - | 19.931s | 23.755 | +| DeepCache w/ T-GATE | 43.868T | - | 14.666s | 23.999 | +| LCM (SD-XL) | 11.955T | 2.570B | 3.805s | 25.044 | +| LCM w/ T-GATE | 11.171T | 2.024B | 3.533s | 25.028 | +| LCM (Pixart-Alpha) | 8.563T | 611.350M | 4.733s | 36.086 | +| LCM w/ T-GATE | 7.623T | 462.585M | 4.543s | 37.048 | + +The latency is tested on an NVIDIA 1080TI, MACs and Params are calculated with [calflops](https://github.com/MrYxJ/calculate-flops.pytorch), and the FID is calculated with [PytorchFID](https://github.com/mseitzer/pytorch-fid). diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/tome.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/tome.md new file mode 100644 index 0000000000000000000000000000000000000000..3e574efbfe1bf4fe7ebb4d06a84ddc8fc60c7fa0 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/tome.md @@ -0,0 +1,96 @@ + + +# Token merging + +[Token merging](https://huggingface.co/papers/2303.17604) (ToMe) merges redundant tokens/patches progressively in the forward pass of a Transformer-based network which can speed-up the inference latency of [`StableDiffusionPipeline`]. + +Install ToMe from `pip`: + +```bash +pip install tomesd +``` + +You can use ToMe from the [`tomesd`](https://github.com/dbolya/tomesd) library with the [`apply_patch`](https://github.com/dbolya/tomesd?tab=readme-ov-file#usage) function: + +```diff + from diffusers import StableDiffusionPipeline + import torch + import tomesd + + pipeline = StableDiffusionPipeline.from_pretrained( + "stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16, use_safetensors=True, + ).to("cuda") ++ tomesd.apply_patch(pipeline, ratio=0.5) + + image = pipeline("a photo of an astronaut riding a horse on mars").images[0] +``` + +The `apply_patch` function exposes a number of [arguments](https://github.com/dbolya/tomesd#usage) to help strike a balance between pipeline inference speed and the quality of the generated tokens. The most important argument is `ratio` which controls the number of tokens that are merged during the forward pass. + +As reported in the [paper](https://huggingface.co/papers/2303.17604), ToMe can greatly preserve the quality of the generated images while boosting inference speed. By increasing the `ratio`, you can speed-up inference even further, but at the cost of some degraded image quality. + +To test the quality of the generated images, we sampled a few prompts from [Parti Prompts](https://parti.research.google/) and performed inference with the [`StableDiffusionPipeline`] with the following settings: + +
+ +
+ +We didn’t notice any significant decrease in the quality of the generated samples, and you can check out the generated samples in this [WandB report](https://wandb.ai/sayakpaul/tomesd-results/runs/23j4bj3i?workspace=). If you're interested in reproducing this experiment, use this [script](https://gist.github.com/sayakpaul/8cac98d7f22399085a060992f411ecbd). + +## Benchmarks + +We also benchmarked the impact of `tomesd` on the [`StableDiffusionPipeline`] with [xFormers](https://huggingface.co/docs/diffusers/optimization/xformers) enabled across several image resolutions. The results are obtained from A100 and V100 GPUs in the following development environment: + +```bash +- `diffusers` version: 0.15.1 +- Python version: 3.8.16 +- PyTorch version (GPU?): 1.13.1+cu116 (True) +- Huggingface_hub version: 0.13.2 +- Transformers version: 4.27.2 +- Accelerate version: 0.18.0 +- xFormers version: 0.0.16 +- tomesd version: 0.1.2 +``` + +To reproduce this benchmark, feel free to use this [script](https://gist.github.com/sayakpaul/27aec6bca7eb7b0e0aa4112205850335). The results are reported in seconds, and where applicable we report the speed-up percentage over the vanilla pipeline when using ToMe and ToMe + xFormers. + +| **GPU** | **Resolution** | **Batch size** | **Vanilla** | **ToMe** | **ToMe + xFormers** | +|----------|----------------|----------------|-------------|----------------|---------------------| +| **A100** | 512 | 10 | 6.88 | 5.26 (+23.55%) | 4.69 (+31.83%) | +| | 768 | 10 | OOM | 14.71 | 11 | +| | | 8 | OOM | 11.56 | 8.84 | +| | | 4 | OOM | 5.98 | 4.66 | +| | | 2 | 4.99 | 3.24 (+35.07%) | 2.1 (+37.88%) | +| | | 1 | 3.29 | 2.24 (+31.91%) | 2.03 (+38.3%) | +| | 1024 | 10 | OOM | OOM | OOM | +| | | 8 | OOM | OOM | OOM | +| | | 4 | OOM | 12.51 | 9.09 | +| | | 2 | OOM | 6.52 | 4.96 | +| | | 1 | 6.4 | 3.61 (+43.59%) | 2.81 (+56.09%) | +| **V100** | 512 | 10 | OOM | 10.03 | 9.29 | +| | | 8 | OOM | 8.05 | 7.47 | +| | | 4 | 5.7 | 4.3 (+24.56%) | 3.98 (+30.18%) | +| | | 2 | 3.14 | 2.43 (+22.61%) | 2.27 (+27.71%) | +| | | 1 | 1.88 | 1.57 (+16.49%) | 1.57 (+16.49%) | +| | 768 | 10 | OOM | OOM | 23.67 | +| | | 8 | OOM | OOM | 18.81 | +| | | 4 | OOM | 11.81 | 9.7 | +| | | 2 | OOM | 6.27 | 5.2 | +| | | 1 | 5.43 | 3.38 (+37.75%) | 2.82 (+48.07%) | +| | 1024 | 10 | OOM | OOM | OOM | +| | | 8 | OOM | OOM | OOM | +| | | 4 | OOM | OOM | 19.35 | +| | | 2 | OOM | 13 | 10.78 | +| | | 1 | OOM | 6.66 | 5.54 | + +As seen in the tables above, the speed-up from `tomesd` becomes more pronounced for larger image resolutions. It is also interesting to note that with `tomesd`, it is possible to run the pipeline on a higher resolution like 1024x1024. You may be able to speed-up inference even more with [`torch.compile`](torch2.0). diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/torch2.0.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/torch2.0.md new file mode 100644 index 0000000000000000000000000000000000000000..cc69eceff3af1d492c1eda48dd329513cb72e22f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/torch2.0.md @@ -0,0 +1,438 @@ + + +# PyTorch 2.0 + +🤗 Diffusers supports the latest optimizations from [PyTorch 2.0](https://pytorch.org/get-started/pytorch-2.0/) which include: + +1. A memory-efficient attention implementation, scaled dot product attention, without requiring any extra dependencies such as xFormers. +2. [`torch.compile`](https://pytorch.org/tutorials/intermediate/torch_compile_tutorial.html), a just-in-time (JIT) compiler to provide an extra performance boost when individual models are compiled. + +Both of these optimizations require PyTorch 2.0 or later and 🤗 Diffusers > 0.13.0. + +```bash +pip install --upgrade torch diffusers +``` + +## Scaled dot product attention + +[`torch.nn.functional.scaled_dot_product_attention`](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention) (SDPA) is an optimized and memory-efficient attention (similar to xFormers) that automatically enables several other optimizations depending on the model inputs and GPU type. SDPA is enabled by default if you're using PyTorch 2.0 and the latest version of 🤗 Diffusers, so you don't need to add anything to your code. + +However, if you want to explicitly enable it, you can set a [`DiffusionPipeline`] to use [`~models.attention_processor.AttnProcessor2_0`]: + +```diff + import torch + from diffusers import DiffusionPipeline ++ from diffusers.models.attention_processor import AttnProcessor2_0 + + pipe = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16, use_safetensors=True).to("cuda") ++ pipe.unet.set_attn_processor(AttnProcessor2_0()) + + prompt = "a photo of an astronaut riding a horse on mars" + image = pipe(prompt).images[0] +``` + +SDPA should be as fast and memory efficient as `xFormers`; check the [benchmark](#benchmark) for more details. + +In some cases - such as making the pipeline more deterministic or converting it to other formats - it may be helpful to use the vanilla attention processor, [`~models.attention_processor.AttnProcessor`]. To revert to [`~models.attention_processor.AttnProcessor`], call the [`~UNet2DConditionModel.set_default_attn_processor`] function on the pipeline: + +```diff + import torch + from diffusers import DiffusionPipeline + + pipe = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16, use_safetensors=True).to("cuda") ++ pipe.unet.set_default_attn_processor() + + prompt = "a photo of an astronaut riding a horse on mars" + image = pipe(prompt).images[0] +``` + +## torch.compile + +The `torch.compile` function can often provide an additional speed-up to your PyTorch code. In 🤗 Diffusers, it is usually best to wrap the UNet with `torch.compile` because it does most of the heavy lifting in the pipeline. + +```python +from diffusers import DiffusionPipeline +import torch + +pipe = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", torch_dtype=torch.float16, use_safetensors=True).to("cuda") +pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True) +images = pipe(prompt, num_inference_steps=steps, num_images_per_prompt=batch_size).images[0] +``` + +Depending on GPU type, `torch.compile` can provide an *additional speed-up* of **5-300x** on top of SDPA! If you're using more recent GPU architectures such as Ampere (A100, 3090), Ada (4090), and Hopper (H100), `torch.compile` is able to squeeze even more performance out of these GPUs. + +Compilation requires some time to complete, so it is best suited for situations where you prepare your pipeline once and then perform the same type of inference operations multiple times. For example, calling the compiled pipeline on a different image size triggers compilation again which can be expensive. + +For more information and different options about `torch.compile`, refer to the [`torch_compile`](https://pytorch.org/tutorials/intermediate/torch_compile_tutorial.html) tutorial. + +> [!TIP] +> Learn more about other ways PyTorch 2.0 can help optimize your model in the [Accelerate inference of text-to-image diffusion models](../tutorials/fast_diffusion) tutorial. + +### Regional compilation + +Compiling the whole model usually has a big problem space for optimization. Models are often composed of multiple repeated blocks. [Regional compilation](https://pytorch.org/tutorials/recipes/regional_compilation.html) compiles the repeated block first (a transformer encoder block, for example), so that the Torch compiler would re-use its cached/optimized generated code for the other blocks, reducing (often massively) the cold start compilation time observed on the first inference call. + +Enabling regional compilation might require simple yet intrusive changes to the +modeling code. However, 🤗 Accelerate provides a utility [`compile_regions()`](https://huggingface.co/docs/accelerate/main/en/usage_guides/compilation#how-to-use-regional-compilation) which automatically compiles +the repeated blocks of the provided `nn.Module` sequentially, and the rest of the model separately. This helps with reducing cold start time while keeping most (if not all) of the speedup you would get from full compilation. + +```py +# Make sure you're on the latest `accelerate`: `pip install -U accelerate`. +from accelerate.utils import compile_regions + +pipe.unet = compile_regions(pipe.unet, mode="reduce-overhead", fullgraph=True) +``` + +As you may have noticed `compile_regions()` takes the same arguments as `torch.compile()`, allowing flexibility. + +## Benchmark + +We conducted a comprehensive benchmark with PyTorch 2.0's efficient attention implementation and `torch.compile` across different GPUs and batch sizes for five of our most used pipelines. The code is benchmarked on 🤗 Diffusers v0.17.0.dev0 to optimize `torch.compile` usage (see [here](https://github.com/huggingface/diffusers/pull/3313) for more details). + +Expand the dropdown below to find the code used to benchmark each pipeline: + +
+ +### Stable Diffusion text-to-image + +```python +from diffusers import DiffusionPipeline +import torch + +path = "stable-diffusion-v1-5/stable-diffusion-v1-5" + +run_compile = True # Set True / False + +pipe = DiffusionPipeline.from_pretrained(path, torch_dtype=torch.float16, use_safetensors=True) +pipe = pipe.to("cuda") +pipe.unet.to(memory_format=torch.channels_last) + +if run_compile: + print("Run torch compile") + pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True) + +prompt = "ghibli style, a fantasy landscape with castles" + +for _ in range(3): + images = pipe(prompt=prompt).images +``` + +### Stable Diffusion image-to-image + +```python +from diffusers import StableDiffusionImg2ImgPipeline +from diffusers.utils import load_image +import torch + +url = "https://raw.githubusercontent.com/CompVis/stable-diffusion/main/assets/stable-samples/img2img/sketch-mountains-input.jpg" + +init_image = load_image(url) +init_image = init_image.resize((512, 512)) + +path = "stable-diffusion-v1-5/stable-diffusion-v1-5" + +run_compile = True # Set True / False + +pipe = StableDiffusionImg2ImgPipeline.from_pretrained(path, torch_dtype=torch.float16, use_safetensors=True) +pipe = pipe.to("cuda") +pipe.unet.to(memory_format=torch.channels_last) + +if run_compile: + print("Run torch compile") + pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True) + +prompt = "ghibli style, a fantasy landscape with castles" + +for _ in range(3): + image = pipe(prompt=prompt, image=init_image).images[0] +``` + +### Stable Diffusion inpainting + +```python +from diffusers import StableDiffusionInpaintPipeline +from diffusers.utils import load_image +import torch + +img_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo.png" +mask_url = "https://raw.githubusercontent.com/CompVis/latent-diffusion/main/data/inpainting_examples/overture-creations-5sI6fQgYIuo_mask.png" + +init_image = load_image(img_url).resize((512, 512)) +mask_image = load_image(mask_url).resize((512, 512)) + +path = "runwayml/stable-diffusion-inpainting" + +run_compile = True # Set True / False + +pipe = StableDiffusionInpaintPipeline.from_pretrained(path, torch_dtype=torch.float16, use_safetensors=True) +pipe = pipe.to("cuda") +pipe.unet.to(memory_format=torch.channels_last) + +if run_compile: + print("Run torch compile") + pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True) + +prompt = "ghibli style, a fantasy landscape with castles" + +for _ in range(3): + image = pipe(prompt=prompt, image=init_image, mask_image=mask_image).images[0] +``` + +### ControlNet + +```python +from diffusers import StableDiffusionControlNetPipeline, ControlNetModel +from diffusers.utils import load_image +import torch + +url = "https://raw.githubusercontent.com/CompVis/stable-diffusion/main/assets/stable-samples/img2img/sketch-mountains-input.jpg" + +init_image = load_image(url) +init_image = init_image.resize((512, 512)) + +path = "stable-diffusion-v1-5/stable-diffusion-v1-5" + +run_compile = True # Set True / False +controlnet = ControlNetModel.from_pretrained("lllyasviel/sd-controlnet-canny", torch_dtype=torch.float16, use_safetensors=True) +pipe = StableDiffusionControlNetPipeline.from_pretrained( + path, controlnet=controlnet, torch_dtype=torch.float16, use_safetensors=True +) + +pipe = pipe.to("cuda") +pipe.unet.to(memory_format=torch.channels_last) +pipe.controlnet.to(memory_format=torch.channels_last) + +if run_compile: + print("Run torch compile") + pipe.unet = torch.compile(pipe.unet, mode="reduce-overhead", fullgraph=True) + pipe.controlnet = torch.compile(pipe.controlnet, mode="reduce-overhead", fullgraph=True) + +prompt = "ghibli style, a fantasy landscape with castles" + +for _ in range(3): + image = pipe(prompt=prompt, image=init_image).images[0] +``` + +### DeepFloyd IF text-to-image + upscaling + +```python +from diffusers import DiffusionPipeline +import torch + +run_compile = True # Set True / False + +pipe_1 = DiffusionPipeline.from_pretrained("DeepFloyd/IF-I-M-v1.0", variant="fp16", text_encoder=None, torch_dtype=torch.float16, use_safetensors=True) +pipe_1.to("cuda") +pipe_2 = DiffusionPipeline.from_pretrained("DeepFloyd/IF-II-M-v1.0", variant="fp16", text_encoder=None, torch_dtype=torch.float16, use_safetensors=True) +pipe_2.to("cuda") +pipe_3 = DiffusionPipeline.from_pretrained("stabilityai/stable-diffusion-x4-upscaler", torch_dtype=torch.float16, use_safetensors=True) +pipe_3.to("cuda") + + +pipe_1.unet.to(memory_format=torch.channels_last) +pipe_2.unet.to(memory_format=torch.channels_last) +pipe_3.unet.to(memory_format=torch.channels_last) + +if run_compile: + pipe_1.unet = torch.compile(pipe_1.unet, mode="reduce-overhead", fullgraph=True) + pipe_2.unet = torch.compile(pipe_2.unet, mode="reduce-overhead", fullgraph=True) + pipe_3.unet = torch.compile(pipe_3.unet, mode="reduce-overhead", fullgraph=True) + +prompt = "the blue hulk" + +prompt_embeds = torch.randn((1, 2, 4096), dtype=torch.float16) +neg_prompt_embeds = torch.randn((1, 2, 4096), dtype=torch.float16) + +for _ in range(3): + image_1 = pipe_1(prompt_embeds=prompt_embeds, negative_prompt_embeds=neg_prompt_embeds, output_type="pt").images + image_2 = pipe_2(image=image_1, prompt_embeds=prompt_embeds, negative_prompt_embeds=neg_prompt_embeds, output_type="pt").images + image_3 = pipe_3(prompt=prompt, image=image_1, noise_level=100).images +``` +
+ +The graph below highlights the relative speed-ups for the [`StableDiffusionPipeline`] across five GPU families with PyTorch 2.0 and `torch.compile` enabled. The benchmarks for the following graphs are measured in *number of iterations/second*. + +![t2i_speedup](https://huggingface.co/datasets/diffusers/docs-images/resolve/main/pt2_benchmarks/t2i_speedup.png) + +To give you an even better idea of how this speed-up holds for the other pipelines, consider the following +graph for an A100 with PyTorch 2.0 and `torch.compile`: + +![a100_numbers](https://huggingface.co/datasets/diffusers/docs-images/resolve/main/pt2_benchmarks/a100_numbers.png) + +In the following tables, we report our findings in terms of the *number of iterations/second*. + +### A100 (batch size: 1) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 21.66 | 23.13 | 44.03 | 49.74 | +| SD - img2img | 21.81 | 22.40 | 43.92 | 46.32 | +| SD - inpaint | 22.24 | 23.23 | 43.76 | 49.25 | +| SD - controlnet | 15.02 | 15.82 | 32.13 | 36.08 | +| IF | 20.21 /
13.84 /
24.00 | 20.12 /
13.70 /
24.03 | ❌ | 97.34 /
27.23 /
111.66 | +| SDXL - txt2img | 8.64 | 9.9 | - | - | + +### A100 (batch size: 4) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 11.6 | 13.12 | 14.62 | 17.27 | +| SD - img2img | 11.47 | 13.06 | 14.66 | 17.25 | +| SD - inpaint | 11.67 | 13.31 | 14.88 | 17.48 | +| SD - controlnet | 8.28 | 9.38 | 10.51 | 12.41 | +| IF | 25.02 | 18.04 | ❌ | 48.47 | +| SDXL - txt2img | 2.44 | 2.74 | - | - | + +### A100 (batch size: 16) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 3.04 | 3.6 | 3.83 | 4.68 | +| SD - img2img | 2.98 | 3.58 | 3.83 | 4.67 | +| SD - inpaint | 3.04 | 3.66 | 3.9 | 4.76 | +| SD - controlnet | 2.15 | 2.58 | 2.74 | 3.35 | +| IF | 8.78 | 9.82 | ❌ | 16.77 | +| SDXL - txt2img | 0.64 | 0.72 | - | - | + +### V100 (batch size: 1) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 18.99 | 19.14 | 20.95 | 22.17 | +| SD - img2img | 18.56 | 19.18 | 20.95 | 22.11 | +| SD - inpaint | 19.14 | 19.06 | 21.08 | 22.20 | +| SD - controlnet | 13.48 | 13.93 | 15.18 | 15.88 | +| IF | 20.01 /
9.08 /
23.34 | 19.79 /
8.98 /
24.10 | ❌ | 55.75 /
11.57 /
57.67 | + +### V100 (batch size: 4) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 5.96 | 5.89 | 6.83 | 6.86 | +| SD - img2img | 5.90 | 5.91 | 6.81 | 6.82 | +| SD - inpaint | 5.99 | 6.03 | 6.93 | 6.95 | +| SD - controlnet | 4.26 | 4.29 | 4.92 | 4.93 | +| IF | 15.41 | 14.76 | ❌ | 22.95 | + +### V100 (batch size: 16) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 1.66 | 1.66 | 1.92 | 1.90 | +| SD - img2img | 1.65 | 1.65 | 1.91 | 1.89 | +| SD - inpaint | 1.69 | 1.69 | 1.95 | 1.93 | +| SD - controlnet | 1.19 | 1.19 | OOM after warmup | 1.36 | +| IF | 5.43 | 5.29 | ❌ | 7.06 | + +### T4 (batch size: 1) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 6.9 | 6.95 | 7.3 | 7.56 | +| SD - img2img | 6.84 | 6.99 | 7.04 | 7.55 | +| SD - inpaint | 6.91 | 6.7 | 7.01 | 7.37 | +| SD - controlnet | 4.89 | 4.86 | 5.35 | 5.48 | +| IF | 17.42 /
2.47 /
18.52 | 16.96 /
2.45 /
18.69 | ❌ | 24.63 /
2.47 /
23.39 | +| SDXL - txt2img | 1.15 | 1.16 | - | - | + +### T4 (batch size: 4) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 1.79 | 1.79 | 2.03 | 1.99 | +| SD - img2img | 1.77 | 1.77 | 2.05 | 2.04 | +| SD - inpaint | 1.81 | 1.82 | 2.09 | 2.09 | +| SD - controlnet | 1.34 | 1.27 | 1.47 | 1.46 | +| IF | 5.79 | 5.61 | ❌ | 7.39 | +| SDXL - txt2img | 0.288 | 0.289 | - | - | + +### T4 (batch size: 16) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 2.34s | 2.30s | OOM after 2nd iteration | 1.99s | +| SD - img2img | 2.35s | 2.31s | OOM after warmup | 2.00s | +| SD - inpaint | 2.30s | 2.26s | OOM after 2nd iteration | 1.95s | +| SD - controlnet | OOM after 2nd iteration | OOM after 2nd iteration | OOM after warmup | OOM after warmup | +| IF * | 1.44 | 1.44 | ❌ | 1.94 | +| SDXL - txt2img | OOM | OOM | - | - | + +### RTX 3090 (batch size: 1) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 22.56 | 22.84 | 23.84 | 25.69 | +| SD - img2img | 22.25 | 22.61 | 24.1 | 25.83 | +| SD - inpaint | 22.22 | 22.54 | 24.26 | 26.02 | +| SD - controlnet | 16.03 | 16.33 | 17.38 | 18.56 | +| IF | 27.08 /
9.07 /
31.23 | 26.75 /
8.92 /
31.47 | ❌ | 68.08 /
11.16 /
65.29 | + +### RTX 3090 (batch size: 4) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 6.46 | 6.35 | 7.29 | 7.3 | +| SD - img2img | 6.33 | 6.27 | 7.31 | 7.26 | +| SD - inpaint | 6.47 | 6.4 | 7.44 | 7.39 | +| SD - controlnet | 4.59 | 4.54 | 5.27 | 5.26 | +| IF | 16.81 | 16.62 | ❌ | 21.57 | + +### RTX 3090 (batch size: 16) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 1.7 | 1.69 | 1.93 | 1.91 | +| SD - img2img | 1.68 | 1.67 | 1.93 | 1.9 | +| SD - inpaint | 1.72 | 1.71 | 1.97 | 1.94 | +| SD - controlnet | 1.23 | 1.22 | 1.4 | 1.38 | +| IF | 5.01 | 5.00 | ❌ | 6.33 | + +### RTX 4090 (batch size: 1) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 40.5 | 41.89 | 44.65 | 49.81 | +| SD - img2img | 40.39 | 41.95 | 44.46 | 49.8 | +| SD - inpaint | 40.51 | 41.88 | 44.58 | 49.72 | +| SD - controlnet | 29.27 | 30.29 | 32.26 | 36.03 | +| IF | 69.71 /
18.78 /
85.49 | 69.13 /
18.80 /
85.56 | ❌ | 124.60 /
26.37 /
138.79 | +| SDXL - txt2img | 6.8 | 8.18 | - | - | + +### RTX 4090 (batch size: 4) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 12.62 | 12.84 | 15.32 | 15.59 | +| SD - img2img | 12.61 | 12,.79 | 15.35 | 15.66 | +| SD - inpaint | 12.65 | 12.81 | 15.3 | 15.58 | +| SD - controlnet | 9.1 | 9.25 | 11.03 | 11.22 | +| IF | 31.88 | 31.14 | ❌ | 43.92 | +| SDXL - txt2img | 2.19 | 2.35 | - | - | + +### RTX 4090 (batch size: 16) + +| **Pipeline** | **torch 2.0 -
no compile** | **torch nightly -
no compile** | **torch 2.0 -
compile** | **torch nightly -
compile** | +|:---:|:---:|:---:|:---:|:---:| +| SD - txt2img | 3.17 | 3.2 | 3.84 | 3.85 | +| SD - img2img | 3.16 | 3.2 | 3.84 | 3.85 | +| SD - inpaint | 3.17 | 3.2 | 3.85 | 3.85 | +| SD - controlnet | 2.23 | 2.3 | 2.7 | 2.75 | +| IF | 9.26 | 9.2 | ❌ | 13.31 | +| SDXL - txt2img | 0.52 | 0.53 | - | - | + +## Notes + +* Follow this [PR](https://github.com/huggingface/diffusers/pull/3313) for more details on the environment used for conducting the benchmarks. +* For the DeepFloyd IF pipeline where batch sizes > 1, we only used a batch size of > 1 in the first IF pipeline for text-to-image generation and NOT for upscaling. That means the two upscaling pipelines received a batch size of 1. + +*Thanks to [Horace He](https://github.com/Chillee) from the PyTorch team for their support in improving our support of `torch.compile()` in Diffusers.* diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/xdit.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/xdit.md new file mode 100644 index 0000000000000000000000000000000000000000..ecf45635684ac0f106833a421e4d573ce1897423 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/xdit.md @@ -0,0 +1,121 @@ +# xDiT + +[xDiT](https://github.com/xdit-project/xDiT) is an inference engine designed for the large scale parallel deployment of Diffusion Transformers (DiTs). xDiT provides a suite of efficient parallel approaches for Diffusion Models, as well as GPU kernel accelerations. + +There are four parallel methods supported in xDiT, including [Unified Sequence Parallelism](https://huggingface.co/papers/2405.07719), [PipeFusion](https://huggingface.co/papers/2405.14430), CFG parallelism and data parallelism. The four parallel methods in xDiT can be configured in a hybrid manner, optimizing communication patterns to best suit the underlying network hardware. + +Optimization orthogonal to parallelization focuses on accelerating single GPU performance. In addition to utilizing well-known Attention optimization libraries, we leverage compilation acceleration technologies such as torch.compile and onediff. + +The overview of xDiT is shown as follows. + +
+ +
+You can install xDiT using the following command: + + +```bash +pip install xfuser +``` + +Here's an example of using xDiT to accelerate inference of a Diffusers model. + +```diff + import torch + from diffusers import StableDiffusion3Pipeline + + from xfuser import xFuserArgs, xDiTParallel + from xfuser.config import FlexibleArgumentParser + from xfuser.core.distributed import get_world_group + + def main(): ++ parser = FlexibleArgumentParser(description="xFuser Arguments") ++ args = xFuserArgs.add_cli_args(parser).parse_args() ++ engine_args = xFuserArgs.from_cli_args(args) ++ engine_config, input_config = engine_args.create_config() + + local_rank = get_world_group().local_rank + pipe = StableDiffusion3Pipeline.from_pretrained( + pretrained_model_name_or_path=engine_config.model_config.model, + torch_dtype=torch.float16, + ).to(f"cuda:{local_rank}") + +# do anything you want with pipeline here + ++ pipe = xDiTParallel(pipe, engine_config, input_config) + + pipe( + height=input_config.height, + width=input_config.height, + prompt=input_config.prompt, + num_inference_steps=input_config.num_inference_steps, + output_type=input_config.output_type, + generator=torch.Generator(device="cuda").manual_seed(input_config.seed), + ) + ++ if input_config.output_type == "pil": ++ pipe.save("results", "stable_diffusion_3") + +if __name__ == "__main__": + main() + +``` + +As you can see, we only need to use xFuserArgs from xDiT to get configuration parameters, and pass these parameters along with the pipeline object from the Diffusers library into xDiTParallel to complete the parallelization of a specific pipeline in Diffusers. + +xDiT runtime parameters can be viewed in the command line using `-h`, and you can refer to this [usage](https://github.com/xdit-project/xDiT?tab=readme-ov-file#2-usage) example for more details. + +xDiT needs to be launched using torchrun to support its multi-node, multi-GPU parallel capabilities. For example, the following command can be used for 8-GPU parallel inference: + +```bash +torchrun --nproc_per_node=8 ./inference.py --model models/FLUX.1-dev --data_parallel_degree 2 --ulysses_degree 2 --ring_degree 2 --prompt "A snowy mountain" "A small dog" --num_inference_steps 50 +``` + +## Supported models + +A subset of Diffusers models are supported in xDiT, such as Flux.1, Stable Diffusion 3, etc. The latest supported models can be found [here](https://github.com/xdit-project/xDiT?tab=readme-ov-file#-supported-dits). + +## Benchmark +We tested different models on various machines, and here is some of the benchmark data. + +### Flux.1-schnell +
+ +
+ + +
+ +
+ +### Stable Diffusion 3 +
+ +
+ +
+ +
+ +### HunyuanDiT +
+ +
+ +
+ +
+ +
+ +
+ +More detailed performance metric can be found on our [github page](https://github.com/xdit-project/xDiT?tab=readme-ov-file#perf). + +## Reference + +[xDiT-project](https://github.com/xdit-project/xDiT) + +[USP: A Unified Sequence Parallelism Approach for Long Context Generative AI](https://huggingface.co/papers/2405.07719) + +[PipeFusion: Displaced Patch Pipeline Parallelism for Inference of Diffusion Transformer Models](https://huggingface.co/papers/2405.14430) \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/xformers.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/xformers.md new file mode 100644 index 0000000000000000000000000000000000000000..4ef0da9e890dcc68d6f4b143d71841c2701d573e --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/optimization/xformers.md @@ -0,0 +1,35 @@ + + +# xFormers + +We recommend [xFormers](https://github.com/facebookresearch/xformers) for both inference and training. In our tests, the optimizations performed in the attention blocks allow for both faster speed and reduced memory consumption. + +Install xFormers from `pip`: + +```bash +pip install xformers +``` + + + +The xFormers `pip` package requires the latest version of PyTorch. If you need to use a previous version of PyTorch, then we recommend [installing xFormers from the source](https://github.com/facebookresearch/xformers#installing-xformers). + + + +After xFormers is installed, you can use `enable_xformers_memory_efficient_attention()` for faster inference and reduced memory consumption as shown in this [section](memory#memory-efficient-attention). + + + +According to this [issue](https://github.com/huggingface/diffusers/issues/2234#issuecomment-1416931212), xFormers `v0.0.16` cannot be used for training (fine-tune or DreamBooth) in some GPUs. If you observe this problem, please install a development version as indicated in the issue comments. + + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/bitsandbytes.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/bitsandbytes.md new file mode 100644 index 0000000000000000000000000000000000000000..b1c130b792c35cc85fc5db36349f5154d5023103 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/bitsandbytes.md @@ -0,0 +1,422 @@ + + +# bitsandbytes + +[bitsandbytes](https://huggingface.co/docs/bitsandbytes/index) is the easiest option for quantizing a model to 8 and 4-bit. 8-bit quantization multiplies outliers in fp16 with non-outliers in int8, converts the non-outlier values back to fp16, and then adds them together to return the weights in fp16. This reduces the degradative effect outlier values have on a model's performance. + +4-bit quantization compresses a model even further, and it is commonly used with [QLoRA](https://hf.co/papers/2305.14314) to finetune quantized LLMs. + +This guide demonstrates how quantization can enable running +[FLUX.1-dev](https://huggingface.co/black-forest-labs/FLUX.1-dev) +on less than 16GB of VRAM and even on a free Google +Colab instance. + +![comparison image](https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/quant-bnb/comparison.png) + +To use bitsandbytes, make sure you have the following libraries installed: + +```bash +pip install diffusers transformers accelerate bitsandbytes -U +``` + +Now you can quantize a model by passing a [`BitsAndBytesConfig`] to [`~ModelMixin.from_pretrained`]. This works for any model in any modality, as long as it supports loading with [Accelerate](https://hf.co/docs/accelerate/index) and contains `torch.nn.Linear` layers. + + + + +Quantizing a model in 8-bit halves the memory-usage: + +bitsandbytes is supported in both Transformers and Diffusers, so you can quantize both the +[`FluxTransformer2DModel`] and [`~transformers.T5EncoderModel`]. + +For Ada and higher-series GPUs. we recommend changing `torch_dtype` to `torch.bfloat16`. + +> [!TIP] +> The [`CLIPTextModel`] and [`AutoencoderKL`] aren't quantized because they're already small in size and because [`AutoencoderKL`] only has a few `torch.nn.Linear` layers. + +```py +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig +from transformers import BitsAndBytesConfig as TransformersBitsAndBytesConfig +import torch +from diffusers import AutoModel +from transformers import T5EncoderModel + +quant_config = TransformersBitsAndBytesConfig(load_in_8bit=True,) + +text_encoder_2_8bit = T5EncoderModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="text_encoder_2", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_8bit=True,) + +transformer_8bit = AutoModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) +``` + +By default, all the other modules such as `torch.nn.LayerNorm` are converted to `torch.float16`. You can change the data type of these modules with the `torch_dtype` parameter. + +```diff +transformer_8bit = AutoModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="transformer", + quantization_config=quant_config, ++ torch_dtype=torch.float32, +) +``` + +Let's generate an image using our quantized models. + +Setting `device_map="auto"` automatically fills all available space on the GPU(s) first, then the +CPU, and finally, the hard drive (the absolute slowest option) if there is still not enough memory. + +```py +from diffusers import FluxPipeline + +pipe = FluxPipeline.from_pretrained( + "black-forest-labs/FLUX.1-dev", + transformer=transformer_8bit, + text_encoder_2=text_encoder_2_8bit, + torch_dtype=torch.float16, + device_map="auto", +) + +pipe_kwargs = { + "prompt": "A cat holding a sign that says hello world", + "height": 1024, + "width": 1024, + "guidance_scale": 3.5, + "num_inference_steps": 50, + "max_sequence_length": 512, +} + +image = pipe(**pipe_kwargs, generator=torch.manual_seed(0),).images[0] +``` + +
+ +
+ +When there is enough memory, you can also directly move the pipeline to the GPU with `.to("cuda")` and apply [`~DiffusionPipeline.enable_model_cpu_offload`] to optimize GPU memory usage. + +Once a model is quantized, you can push the model to the Hub with the [`~ModelMixin.push_to_hub`] method. The quantization `config.json` file is pushed first, followed by the quantized model weights. You can also save the serialized 8-bit models locally with [`~ModelMixin.save_pretrained`]. + +
+ + +Quantizing a model in 4-bit reduces your memory-usage by 4x: + +bitsandbytes is supported in both Transformers and Diffusers, so you can can quantize both the +[`FluxTransformer2DModel`] and [`~transformers.T5EncoderModel`]. + +For Ada and higher-series GPUs. we recommend changing `torch_dtype` to `torch.bfloat16`. + +> [!TIP] +> The [`CLIPTextModel`] and [`AutoencoderKL`] aren't quantized because they're already small in size and because [`AutoencoderKL`] only has a few `torch.nn.Linear` layers. + +```py +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig +from transformers import BitsAndBytesConfig as TransformersBitsAndBytesConfig +import torch +from diffusers import AutoModel +from transformers import T5EncoderModel + +quant_config = TransformersBitsAndBytesConfig(load_in_4bit=True,) + +text_encoder_2_4bit = T5EncoderModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="text_encoder_2", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig(load_in_4bit=True,) + +transformer_4bit = AutoModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) +``` + +By default, all the other modules such as `torch.nn.LayerNorm` are converted to `torch.float16`. You can change the data type of these modules with the `torch_dtype` parameter. + +```diff +transformer_4bit = AutoModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="transformer", + quantization_config=quant_config, ++ torch_dtype=torch.float32, +) +``` + +Let's generate an image using our quantized models. + +Setting `device_map="auto"` automatically fills all available space on the GPU(s) first, then the CPU, and finally, the hard drive (the absolute slowest option) if there is still not enough memory. + +```py +from diffusers import FluxPipeline + +pipe = FluxPipeline.from_pretrained( + "black-forest-labs/FLUX.1-dev", + transformer=transformer_4bit, + text_encoder_2=text_encoder_2_4bit, + torch_dtype=torch.float16, + device_map="auto", +) + +pipe_kwargs = { + "prompt": "A cat holding a sign that says hello world", + "height": 1024, + "width": 1024, + "guidance_scale": 3.5, + "num_inference_steps": 50, + "max_sequence_length": 512, +} + +image = pipe(**pipe_kwargs, generator=torch.manual_seed(0),).images[0] +``` + +
+ +
+ +When there is enough memory, you can also directly move the pipeline to the GPU with `.to("cuda")` and apply [`~DiffusionPipeline.enable_model_cpu_offload`] to optimize GPU memory usage. + +Once a model is quantized, you can push the model to the Hub with the [`~ModelMixin.push_to_hub`] method. The quantization `config.json` file is pushed first, followed by the quantized model weights. You can also save the serialized 4-bit models locally with [`~ModelMixin.save_pretrained`]. + +
+
+ + + +Training with 8-bit and 4-bit weights are only supported for training *extra* parameters. + + + +Check your memory footprint with the `get_memory_footprint` method: + +```py +print(model.get_memory_footprint()) +``` + +Note that this only tells you the memory footprint of the model params and does _not_ estimate the inference memory requirements. + +Quantized models can be loaded from the [`~ModelMixin.from_pretrained`] method without needing to specify the `quantization_config` parameters: + +```py +from diffusers import AutoModel, BitsAndBytesConfig + +quantization_config = BitsAndBytesConfig(load_in_4bit=True) + +model_4bit = AutoModel.from_pretrained( + "hf-internal-testing/flux.1-dev-nf4-pkg", subfolder="transformer" +) +``` + +## 8-bit (LLM.int8() algorithm) + + + +Learn more about the details of 8-bit quantization in this [blog post](https://huggingface.co/blog/hf-bitsandbytes-integration)! + + + +This section explores some of the specific features of 8-bit models, such as outlier thresholds and skipping module conversion. + +### Outlier threshold + +An "outlier" is a hidden state value greater than a certain threshold, and these values are computed in fp16. While the values are usually normally distributed ([-3.5, 3.5]), this distribution can be very different for large models ([-60, 6] or [6, 60]). 8-bit quantization works well for values ~5, but beyond that, there is a significant performance penalty. A good default threshold value is 6, but a lower threshold may be needed for more unstable models (small models or finetuning). + +To find the best threshold for your model, we recommend experimenting with the `llm_int8_threshold` parameter in [`BitsAndBytesConfig`]: + +```py +from diffusers import AutoModel, BitsAndBytesConfig + +quantization_config = BitsAndBytesConfig( + load_in_8bit=True, llm_int8_threshold=10, +) + +model_8bit = AutoModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="transformer", + quantization_config=quantization_config, +) +``` + +### Skip module conversion + +For some models, you don't need to quantize every module to 8-bit which can actually cause instability. For example, for diffusion models like [Stable Diffusion 3](../api/pipelines/stable_diffusion/stable_diffusion_3), the `proj_out` module can be skipped using the `llm_int8_skip_modules` parameter in [`BitsAndBytesConfig`]: + +```py +from diffusers import SD3Transformer2DModel, BitsAndBytesConfig + +quantization_config = BitsAndBytesConfig( + load_in_8bit=True, llm_int8_skip_modules=["proj_out"], +) + +model_8bit = SD3Transformer2DModel.from_pretrained( + "stabilityai/stable-diffusion-3-medium-diffusers", + subfolder="transformer", + quantization_config=quantization_config, +) +``` + + +## 4-bit (QLoRA algorithm) + + + +Learn more about its details in this [blog post](https://huggingface.co/blog/4bit-transformers-bitsandbytes). + + + +This section explores some of the specific features of 4-bit models, such as changing the compute data type, using the Normal Float 4 (NF4) data type, and using nested quantization. + + +### Compute data type + +To speedup computation, you can change the data type from float32 (the default value) to bf16 using the `bnb_4bit_compute_dtype` parameter in [`BitsAndBytesConfig`]: + +```py +import torch +from diffusers import BitsAndBytesConfig + +quantization_config = BitsAndBytesConfig(load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16) +``` + +### Normal Float 4 (NF4) + +NF4 is a 4-bit data type from the [QLoRA](https://hf.co/papers/2305.14314) paper, adapted for weights initialized from a normal distribution. You should use NF4 for training 4-bit base models. This can be configured with the `bnb_4bit_quant_type` parameter in the [`BitsAndBytesConfig`]: + +```py +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig +from transformers import BitsAndBytesConfig as TransformersBitsAndBytesConfig + +from diffusers import AutoModel +from transformers import T5EncoderModel + +quant_config = TransformersBitsAndBytesConfig( + load_in_4bit=True, + bnb_4bit_quant_type="nf4", +) + +text_encoder_2_4bit = T5EncoderModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="text_encoder_2", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig( + load_in_4bit=True, + bnb_4bit_quant_type="nf4", +) + +transformer_4bit = AutoModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) +``` + +For inference, the `bnb_4bit_quant_type` does not have a huge impact on performance. However, to remain consistent with the model weights, you should use the `bnb_4bit_compute_dtype` and `torch_dtype` values. + +### Nested quantization + +Nested quantization is a technique that can save additional memory at no additional performance cost. This feature performs a second quantization of the already quantized weights to save an additional 0.4 bits/parameter. + +```py +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig +from transformers import BitsAndBytesConfig as TransformersBitsAndBytesConfig + +from diffusers import AutoModel +from transformers import T5EncoderModel + +quant_config = TransformersBitsAndBytesConfig( + load_in_4bit=True, + bnb_4bit_use_double_quant=True, +) + +text_encoder_2_4bit = T5EncoderModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="text_encoder_2", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig( + load_in_4bit=True, + bnb_4bit_use_double_quant=True, +) + +transformer_4bit = AutoModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) +``` + +## Dequantizing `bitsandbytes` models + +Once quantized, you can dequantize a model to its original precision, but this might result in a small loss of quality. Make sure you have enough GPU RAM to fit the dequantized model. + +```python +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig +from transformers import BitsAndBytesConfig as TransformersBitsAndBytesConfig + +from diffusers import AutoModel +from transformers import T5EncoderModel + +quant_config = TransformersBitsAndBytesConfig( + load_in_4bit=True, + bnb_4bit_use_double_quant=True, +) + +text_encoder_2_4bit = T5EncoderModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="text_encoder_2", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +quant_config = DiffusersBitsAndBytesConfig( + load_in_4bit=True, + bnb_4bit_use_double_quant=True, +) + +transformer_4bit = AutoModel.from_pretrained( + "black-forest-labs/FLUX.1-dev", + subfolder="transformer", + quantization_config=quant_config, + torch_dtype=torch.float16, +) + +text_encoder_2_4bit.dequantize() +transformer_4bit.dequantize() +``` + +## Resources + +* [End-to-end notebook showing Flux.1 Dev inference in a free-tier Colab](https://gist.github.com/sayakpaul/c76bd845b48759e11687ac550b99d8b4) +* [Training](https://github.com/huggingface/diffusers/blob/8c661ea586bf11cb2440da740dd3c4cf84679b85/examples/dreambooth/README_hidream.md#using-quantization) \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/gguf.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/gguf.md new file mode 100644 index 0000000000000000000000000000000000000000..f7537d7e7882766437ae7cb739b35b8d9908c1e1 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/gguf.md @@ -0,0 +1,69 @@ + + +# GGUF + +The GGUF file format is typically used to store models for inference with [GGML](https://github.com/ggerganov/ggml) and supports a variety of block wise quantization options. Diffusers supports loading checkpoints prequantized and saved in the GGUF format via `from_single_file` loading with Model classes. Loading GGUF checkpoints via Pipelines is currently not supported. + +The following example will load the [FLUX.1 DEV](https://huggingface.co/black-forest-labs/FLUX.1-dev) transformer model using the GGUF Q2_K quantization variant. + +Before starting please install gguf in your environment + +```shell +pip install -U gguf +``` + +Since GGUF is a single file format, use [`~FromSingleFileMixin.from_single_file`] to load the model and pass in the [`GGUFQuantizationConfig`]. + +When using GGUF checkpoints, the quantized weights remain in a low memory `dtype`(typically `torch.uint8`) and are dynamically dequantized and cast to the configured `compute_dtype` during each module's forward pass through the model. The `GGUFQuantizationConfig` allows you to set the `compute_dtype`. + +The functions used for dynamic dequantizatation are based on the great work done by [city96](https://github.com/city96/ComfyUI-GGUF), who created the Pytorch ports of the original [`numpy`](https://github.com/ggerganov/llama.cpp/blob/master/gguf-py/gguf/quants.py) implementation by [compilade](https://github.com/compilade). + +```python +import torch + +from diffusers import FluxPipeline, FluxTransformer2DModel, GGUFQuantizationConfig + +ckpt_path = ( + "https://huggingface.co/city96/FLUX.1-dev-gguf/blob/main/flux1-dev-Q2_K.gguf" +) +transformer = FluxTransformer2DModel.from_single_file( + ckpt_path, + quantization_config=GGUFQuantizationConfig(compute_dtype=torch.bfloat16), + torch_dtype=torch.bfloat16, +) +pipe = FluxPipeline.from_pretrained( + "black-forest-labs/FLUX.1-dev", + transformer=transformer, + torch_dtype=torch.bfloat16, +) +pipe.enable_model_cpu_offload() +prompt = "A cat holding a sign that says hello world" +image = pipe(prompt, generator=torch.manual_seed(0)).images[0] +image.save("flux-gguf.png") +``` + +## Supported Quantization Types + +- BF16 +- Q4_0 +- Q4_1 +- Q5_0 +- Q5_1 +- Q8_0 +- Q2_K +- Q3_K +- Q4_K +- Q5_K +- Q6_K + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/overview.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/overview.md new file mode 100644 index 0000000000000000000000000000000000000000..cc5a7e2891bb445cca1363e594892aa98150789f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/overview.md @@ -0,0 +1,132 @@ + + +# Quantization + +Quantization focuses on representing data with fewer bits while also trying to preserve the precision of the original data. This often means converting a data type to represent the same information with fewer bits. For example, if your model weights are stored as 32-bit floating points and they're quantized to 16-bit floating points, this halves the model size which makes it easier to store and reduces memory usage. Lower precision can also speedup inference because it takes less time to perform calculations with fewer bits. + +Diffusers supports multiple quantization backends to make large diffusion models like [Flux](../api/pipelines/flux) more accessible. This guide shows how to use the [`~quantizers.PipelineQuantizationConfig`] class to quantize a pipeline during its initialization from a pretrained or non-quantized checkpoint. + +## Pipeline-level quantization + +There are two ways you can use [`~quantizers.PipelineQuantizationConfig`] depending on the level of control you want over the quantization specifications of each model in the pipeline. + +- for more basic and simple use cases, you only need to define the `quant_backend`, `quant_kwargs`, and `components_to_quantize` +- for more granular quantization control, provide a `quant_mapping` that provides the quantization specifications for the individual model components + +### Simple quantization + +Initialize [`~quantizers.PipelineQuantizationConfig`] with the following parameters. + +- `quant_backend` specifies which quantization backend to use. Currently supported backends include: `bitsandbytes_4bit`, `bitsandbytes_8bit`, `gguf`, `quanto`, and `torchao`. +- `quant_kwargs` contains the specific quantization arguments to use. +- `components_to_quantize` specifies which components of the pipeline to quantize. Typically, you should quantize the most compute intensive components like the transformer. The text encoder is another component to consider quantizing if a pipeline has more than one such as [`FluxPipeline`]. The example below quantizes the T5 text encoder in [`FluxPipeline`] while keeping the CLIP model intact. + +```py +import torch +from diffusers import DiffusionPipeline +from diffusers.quantizers import PipelineQuantizationConfig + +pipeline_quant_config = PipelineQuantizationConfig( + quant_backend="bitsandbytes_4bit", + quant_kwargs={"load_in_4bit": True, "bnb_4bit_quant_type": "nf4", "bnb_4bit_compute_dtype": torch.bfloat16}, + components_to_quantize=["transformer", "text_encoder_2"], +) +``` + +Pass the `pipeline_quant_config` to [`~DiffusionPipeline.from_pretrained`] to quantize the pipeline. + +```py +pipe = DiffusionPipeline.from_pretrained( + "black-forest-labs/FLUX.1-dev", + quantization_config=pipeline_quant_config, + torch_dtype=torch.bfloat16, +).to("cuda") + +image = pipe("photo of a cute dog").images[0] +``` + +### quant_mapping + +The `quant_mapping` argument provides more flexible options for how to quantize each individual component in a pipeline, like combining different quantization backends. + +Initialize [`~quantizers.PipelineQuantizationConfig`] and pass a `quant_mapping` to it. The `quant_mapping` allows you to specify the quantization options for each component in the pipeline such as the transformer and text encoder. + +The example below uses two quantization backends, [`~quantizers.QuantoConfig`] and [`transformers.BitsAndBytesConfig`], for the transformer and text encoder. + +```py +import torch +from diffusers import DiffusionPipeline +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig +from diffusers.quantizers.quantization_config import QuantoConfig +from diffusers.quantizers import PipelineQuantizationConfig +from transformers import BitsAndBytesConfig as TransformersBitsAndBytesConfig + +pipeline_quant_config = PipelineQuantizationConfig( + quant_mapping={ + "transformer": QuantoConfig(weights_dtype="int8"), + "text_encoder_2": TransformersBitsAndBytesConfig( + load_in_4bit=True, compute_dtype=torch.bfloat16 + ), + } +) +``` + +There is a separate bitsandbytes backend in [Transformers](https://huggingface.co/docs/transformers/main_classes/quantization#transformers.BitsAndBytesConfig). You need to import and use [`transformers.BitsAndBytesConfig`] for components that come from Transformers. For example, `text_encoder_2` in [`FluxPipeline`] is a [`~transformers.T5EncoderModel`] from Transformers so you need to use [`transformers.BitsAndBytesConfig`] instead of [`diffusers.BitsAndBytesConfig`]. + +> [!TIP] +> Use the [simple quantization](#simple-quantization) method above if you don't want to manage these distinct imports or aren't sure where each pipeline component comes from. + +```py +import torch +from diffusers import DiffusionPipeline +from diffusers import BitsAndBytesConfig as DiffusersBitsAndBytesConfig +from diffusers.quantizers import PipelineQuantizationConfig +from transformers import BitsAndBytesConfig as TransformersBitsAndBytesConfig + +pipeline_quant_config = PipelineQuantizationConfig( + quant_mapping={ + "transformer": DiffusersBitsAndBytesConfig(load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16), + "text_encoder_2": TransformersBitsAndBytesConfig( + load_in_4bit=True, compute_dtype=torch.bfloat16 + ), + } +) +``` + +Pass the `pipeline_quant_config` to [`~DiffusionPipeline.from_pretrained`] to quantize the pipeline. + +```py +pipe = DiffusionPipeline.from_pretrained( + "black-forest-labs/FLUX.1-dev", + quantization_config=pipeline_quant_config, + torch_dtype=torch.bfloat16, +).to("cuda") + +image = pipe("photo of a cute dog").images[0] +``` + +## Resources + +Check out the resources below to learn more about quantization. + +- If you are new to quantization, we recommend checking out the following beginner-friendly courses in collaboration with DeepLearning.AI. + + - [Quantization Fundamentals with Hugging Face](https://www.deeplearning.ai/short-courses/quantization-fundamentals-with-hugging-face/) + - [Quantization in Depth](https://www.deeplearning.ai/short-courses/quantization-in-depth/) + +- Refer to the [Contribute new quantization method guide](https://huggingface.co/docs/transformers/main/en/quantization/contribute) if you're interested in adding a new quantization method. + +- The Transformers quantization [Overview](https://huggingface.co/docs/transformers/quantization/overview#when-to-use-what) provides an overview of the pros and cons of different quantization backends. + +- Read the [Exploring Quantization Backends in Diffusers](https://huggingface.co/blog/diffusers-quantization) blog post for a brief introduction to each quantization backend, how to choose a backend, and combining quantization with other memory optimizations. \ No newline at end of file diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/quanto.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/quanto.md new file mode 100644 index 0000000000000000000000000000000000000000..d322d76be267dcf73de5c7f81d7f7ea9e3584b6a --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/quanto.md @@ -0,0 +1,148 @@ + + +# Quanto + +[Quanto](https://github.com/huggingface/optimum-quanto) is a PyTorch quantization backend for [Optimum](https://huggingface.co/docs/optimum/en/index). It has been designed with versatility and simplicity in mind: + +- All features are available in eager mode (works with non-traceable models) +- Supports quantization aware training +- Quantized models are compatible with `torch.compile` +- Quantized models are Device agnostic (e.g CUDA,XPU,MPS,CPU) + +In order to use the Quanto backend, you will first need to install `optimum-quanto>=0.2.6` and `accelerate` + +```shell +pip install optimum-quanto accelerate +``` + +Now you can quantize a model by passing the `QuantoConfig` object to the `from_pretrained()` method. Although the Quanto library does allow quantizing `nn.Conv2d` and `nn.LayerNorm` modules, currently, Diffusers only supports quantizing the weights in the `nn.Linear` layers of a model. The following snippet demonstrates how to apply `float8` quantization with Quanto. + +```python +import torch +from diffusers import FluxTransformer2DModel, QuantoConfig + +model_id = "black-forest-labs/FLUX.1-dev" +quantization_config = QuantoConfig(weights_dtype="float8") +transformer = FluxTransformer2DModel.from_pretrained( + model_id, + subfolder="transformer", + quantization_config=quantization_config, + torch_dtype=torch.bfloat16, +) + +pipe = FluxPipeline.from_pretrained(model_id, transformer=transformer, torch_dtype=torch_dtype) +pipe.to("cuda") + +prompt = "A cat holding a sign that says hello world" +image = pipe( + prompt, num_inference_steps=50, guidance_scale=4.5, max_sequence_length=512 +).images[0] +image.save("output.png") +``` + +## Skipping Quantization on specific modules + +It is possible to skip applying quantization on certain modules using the `modules_to_not_convert` argument in the `QuantoConfig`. Please ensure that the modules passed in to this argument match the keys of the modules in the `state_dict` + +```python +import torch +from diffusers import FluxTransformer2DModel, QuantoConfig + +model_id = "black-forest-labs/FLUX.1-dev" +quantization_config = QuantoConfig(weights_dtype="float8", modules_to_not_convert=["proj_out"]) +transformer = FluxTransformer2DModel.from_pretrained( + model_id, + subfolder="transformer", + quantization_config=quantization_config, + torch_dtype=torch.bfloat16, +) +``` + +## Using `from_single_file` with the Quanto Backend + +`QuantoConfig` is compatible with `~FromOriginalModelMixin.from_single_file`. + +```python +import torch +from diffusers import FluxTransformer2DModel, QuantoConfig + +ckpt_path = "https://huggingface.co/black-forest-labs/FLUX.1-dev/blob/main/flux1-dev.safetensors" +quantization_config = QuantoConfig(weights_dtype="float8") +transformer = FluxTransformer2DModel.from_single_file(ckpt_path, quantization_config=quantization_config, torch_dtype=torch.bfloat16) +``` + +## Saving Quantized models + +Diffusers supports serializing Quanto models using the `~ModelMixin.save_pretrained` method. + +The serialization and loading requirements are different for models quantized directly with the Quanto library and models quantized +with Diffusers using Quanto as the backend. It is currently not possible to load models quantized directly with Quanto into Diffusers using `~ModelMixin.from_pretrained` + +```python +import torch +from diffusers import FluxTransformer2DModel, QuantoConfig + +model_id = "black-forest-labs/FLUX.1-dev" +quantization_config = QuantoConfig(weights_dtype="float8") +transformer = FluxTransformer2DModel.from_pretrained( + model_id, + subfolder="transformer", + quantization_config=quantization_config, + torch_dtype=torch.bfloat16, +) +# save quantized model to reuse +transformer.save_pretrained("") + +# you can reload your quantized model with +model = FluxTransformer2DModel.from_pretrained("") +``` + +## Using `torch.compile` with Quanto + +Currently the Quanto backend supports `torch.compile` for the following quantization types: + +- `int8` weights + +```python +import torch +from diffusers import FluxPipeline, FluxTransformer2DModel, QuantoConfig + +model_id = "black-forest-labs/FLUX.1-dev" +quantization_config = QuantoConfig(weights_dtype="int8") +transformer = FluxTransformer2DModel.from_pretrained( + model_id, + subfolder="transformer", + quantization_config=quantization_config, + torch_dtype=torch.bfloat16, +) +transformer = torch.compile(transformer, mode="max-autotune", fullgraph=True) + +pipe = FluxPipeline.from_pretrained( + model_id, transformer=transformer, torch_dtype=torch_dtype +) +pipe.to("cuda") +images = pipe("A cat holding a sign that says hello").images[0] +images.save("flux-quanto-compile.png") +``` + +## Supported Quantization Types + +### Weights + +- float8 +- int8 +- int4 +- int2 + + diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/torchao.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/torchao.md new file mode 100644 index 0000000000000000000000000000000000000000..3ccca02825888f053d3da36e9bcfe59c9f8156bf --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quantization/torchao.md @@ -0,0 +1,159 @@ + + +# torchao + +[TorchAO](https://github.com/pytorch/ao) is an architecture optimization library for PyTorch. It provides high-performance dtypes, optimization techniques, and kernels for inference and training, featuring composability with native PyTorch features like [torch.compile](https://pytorch.org/tutorials/intermediate/torch_compile_tutorial.html), FullyShardedDataParallel (FSDP), and more. + +Before you begin, make sure you have Pytorch 2.5+ and TorchAO installed. + +```bash +pip install -U torch torchao +``` + + +Quantize a model by passing [`TorchAoConfig`] to [`~ModelMixin.from_pretrained`] (you can also load pre-quantized models). This works for any model in any modality, as long as it supports loading with [Accelerate](https://hf.co/docs/accelerate/index) and contains `torch.nn.Linear` layers. + +The example below only quantizes the weights to int8. + +```python +import torch +from diffusers import FluxPipeline, AutoModel, TorchAoConfig + +model_id = "black-forest-labs/FLUX.1-dev" +dtype = torch.bfloat16 + +quantization_config = TorchAoConfig("int8wo") +transformer = AutoModel.from_pretrained( + model_id, + subfolder="transformer", + quantization_config=quantization_config, + torch_dtype=dtype, +) +pipe = FluxPipeline.from_pretrained( + model_id, + transformer=transformer, + torch_dtype=dtype, +) +pipe.to("cuda") + +# Without quantization: ~31.447 GB +# With quantization: ~20.40 GB +print(f"Pipeline memory usage: {torch.cuda.max_memory_reserved() / 1024**3:.3f} GB") + +prompt = "A cat holding a sign that says hello world" +image = pipe( + prompt, num_inference_steps=50, guidance_scale=4.5, max_sequence_length=512 +).images[0] +image.save("output.png") +``` + +TorchAO is fully compatible with [torch.compile](./optimization/torch2.0#torchcompile), setting it apart from other quantization methods. This makes it easy to speed up inference with just one line of code. + +```python +# In the above code, add the following after initializing the transformer +transformer = torch.compile(transformer, mode="max-autotune", fullgraph=True) +``` + +For speed and memory benchmarks on Flux and CogVideoX, please refer to the table [here](https://github.com/huggingface/diffusers/pull/10009#issue-2688781450). You can also find some torchao [benchmarks](https://github.com/pytorch/ao/tree/main/torchao/quantization#benchmarks) numbers for various hardware. + +torchao also supports an automatic quantization API through [autoquant](https://github.com/pytorch/ao/blob/main/torchao/quantization/README.md#autoquantization). Autoquantization determines the best quantization strategy applicable to a model by comparing the performance of each technique on chosen input types and shapes. Currently, this can be used directly on the underlying modeling components. Diffusers will also expose an autoquant configuration option in the future. + +The `TorchAoConfig` class accepts three parameters: +- `quant_type`: A string value mentioning one of the quantization types below. +- `modules_to_not_convert`: A list of module full/partial module names for which quantization should not be performed. For example, to not perform any quantization of the [`FluxTransformer2DModel`]'s first block, one would specify: `modules_to_not_convert=["single_transformer_blocks.0"]`. +- `kwargs`: A dict of keyword arguments to pass to the underlying quantization method which will be invoked based on `quant_type`. + +## Supported quantization types + +torchao supports weight-only quantization and weight and dynamic-activation quantization for int8, float3-float8, and uint1-uint7. + +Weight-only quantization stores the model weights in a specific low-bit data type but performs computation with a higher-precision data type, like `bfloat16`. This lowers the memory requirements from model weights but retains the memory peaks for activation computation. + +Dynamic activation quantization stores the model weights in a low-bit dtype, while also quantizing the activations on-the-fly to save additional memory. This lowers the memory requirements from model weights, while also lowering the memory overhead from activation computations. However, this may come at a quality tradeoff at times, so it is recommended to test different models thoroughly. + +The quantization methods supported are as follows: + +| **Category** | **Full Function Names** | **Shorthands** | +|--------------|-------------------------|----------------| +| **Integer quantization** | `int4_weight_only`, `int8_dynamic_activation_int4_weight`, `int8_weight_only`, `int8_dynamic_activation_int8_weight` | `int4wo`, `int4dq`, `int8wo`, `int8dq` | +| **Floating point 8-bit quantization** | `float8_weight_only`, `float8_dynamic_activation_float8_weight`, `float8_static_activation_float8_weight` | `float8wo`, `float8wo_e5m2`, `float8wo_e4m3`, `float8dq`, `float8dq_e4m3`, `float8dq_e4m3_tensor`, `float8dq_e4m3_row` | +| **Floating point X-bit quantization** | `fpx_weight_only` | `fpX_eAwB` where `X` is the number of bits (1-7), `A` is exponent bits, and `B` is mantissa bits. Constraint: `X == A + B + 1` | +| **Unsigned Integer quantization** | `uintx_weight_only` | `uint1wo`, `uint2wo`, `uint3wo`, `uint4wo`, `uint5wo`, `uint6wo`, `uint7wo` | + +Some quantization methods are aliases (for example, `int8wo` is the commonly used shorthand for `int8_weight_only`). This allows using the quantization methods described in the torchao docs as-is, while also making it convenient to remember their shorthand notations. + +Refer to the official torchao documentation for a better understanding of the available quantization methods and the exhaustive list of configuration options available. + +## Serializing and Deserializing quantized models + +To serialize a quantized model in a given dtype, first load the model with the desired quantization dtype and then save it using the [`~ModelMixin.save_pretrained`] method. + +```python +import torch +from diffusers import AutoModel, TorchAoConfig + +quantization_config = TorchAoConfig("int8wo") +transformer = AutoModel.from_pretrained( + "black-forest-labs/Flux.1-Dev", + subfolder="transformer", + quantization_config=quantization_config, + torch_dtype=torch.bfloat16, +) +transformer.save_pretrained("/path/to/flux_int8wo", safe_serialization=False) +``` + +To load a serialized quantized model, use the [`~ModelMixin.from_pretrained`] method. + +```python +import torch +from diffusers import FluxPipeline, AutoModel + +transformer = AutoModel.from_pretrained("/path/to/flux_int8wo", torch_dtype=torch.bfloat16, use_safetensors=False) +pipe = FluxPipeline.from_pretrained("black-forest-labs/Flux.1-Dev", transformer=transformer, torch_dtype=torch.bfloat16) +pipe.to("cuda") + +prompt = "A cat holding a sign that says hello world" +image = pipe(prompt, num_inference_steps=30, guidance_scale=7.0).images[0] +image.save("output.png") +``` + +If you are using `torch<=2.6.0`, some quantization methods, such as `uint4wo`, cannot be loaded directly and may result in an `UnpicklingError` when trying to load the models, but work as expected when saving them. In order to work around this, one can load the state dict manually into the model. Note, however, that this requires using `weights_only=False` in `torch.load`, so it should be run only if the weights were obtained from a trustable source. + +```python +import torch +from accelerate import init_empty_weights +from diffusers import FluxPipeline, AutoModel, TorchAoConfig + +# Serialize the model +transformer = AutoModel.from_pretrained( + "black-forest-labs/Flux.1-Dev", + subfolder="transformer", + quantization_config=TorchAoConfig("uint4wo"), + torch_dtype=torch.bfloat16, +) +transformer.save_pretrained("/path/to/flux_uint4wo", safe_serialization=False, max_shard_size="50GB") +# ... + +# Load the model +state_dict = torch.load("/path/to/flux_uint4wo/diffusion_pytorch_model.bin", weights_only=False, map_location="cpu") +with init_empty_weights(): + transformer = AutoModel.from_config("/path/to/flux_uint4wo/config.json") +transformer.load_state_dict(state_dict, strict=True, assign=True) +``` + +> [!TIP] +> The [`AutoModel`] API is supported for PyTorch >= 2.6 as shown in the examples below. + +## Resources + +- [TorchAO Quantization API](https://github.com/pytorch/ao/blob/main/torchao/quantization/README.md) +- [Diffusers-TorchAO examples](https://github.com/sayakpaul/diffusers-torchao) diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quicktour.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quicktour.md new file mode 100644 index 0000000000000000000000000000000000000000..14f567d461636d5ebf326723fdaf03c1f1e395eb --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/quicktour.md @@ -0,0 +1,323 @@ + + +[[open-in-colab]] + +# Quicktour + +Diffusion models are trained to denoise random Gaussian noise step-by-step to generate a sample of interest, such as an image or audio. This has sparked a tremendous amount of interest in generative AI, and you have probably seen examples of diffusion generated images on the internet. 🧨 Diffusers is a library aimed at making diffusion models widely accessible to everyone. + +Whether you're a developer or an everyday user, this quicktour will introduce you to 🧨 Diffusers and help you get up and generating quickly! There are three main components of the library to know about: + +* The [`DiffusionPipeline`] is a high-level end-to-end class designed to rapidly generate samples from pretrained diffusion models for inference. +* Popular pretrained [model](./api/models) architectures and modules that can be used as building blocks for creating diffusion systems. +* Many different [schedulers](./api/schedulers/overview) - algorithms that control how noise is added for training, and how to generate denoised images during inference. + +The quicktour will show you how to use the [`DiffusionPipeline`] for inference, and then walk you through how to combine a model and scheduler to replicate what's happening inside the [`DiffusionPipeline`]. + + + +The quicktour is a simplified version of the introductory 🧨 Diffusers [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/diffusers/diffusers_intro.ipynb) to help you get started quickly. If you want to learn more about 🧨 Diffusers' goal, design philosophy, and additional details about its core API, check out the notebook! + + + +Before you begin, make sure you have all the necessary libraries installed: + +```py +# uncomment to install the necessary libraries in Colab +#!pip install --upgrade diffusers accelerate transformers +``` + +- [🤗 Accelerate](https://huggingface.co/docs/accelerate/index) speeds up model loading for inference and training. +- [🤗 Transformers](https://huggingface.co/docs/transformers/index) is required to run the most popular diffusion models, such as [Stable Diffusion](https://huggingface.co/docs/diffusers/api/pipelines/stable_diffusion/overview). + +## DiffusionPipeline + +The [`DiffusionPipeline`] is the easiest way to use a pretrained diffusion system for inference. It is an end-to-end system containing the model and the scheduler. You can use the [`DiffusionPipeline`] out-of-the-box for many tasks. Take a look at the table below for some supported tasks, and for a complete list of supported tasks, check out the [🧨 Diffusers Summary](./api/pipelines/overview#diffusers-summary) table. + +| **Task** | **Description** | **Pipeline** +|------------------------------|--------------------------------------------------------------------------------------------------------------|-----------------| +| Unconditional Image Generation | generate an image from Gaussian noise | [unconditional_image_generation](./using-diffusers/unconditional_image_generation) | +| Text-Guided Image Generation | generate an image given a text prompt | [conditional_image_generation](./using-diffusers/conditional_image_generation) | +| Text-Guided Image-to-Image Translation | adapt an image guided by a text prompt | [img2img](./using-diffusers/img2img) | +| Text-Guided Image-Inpainting | fill the masked part of an image given the image, the mask and a text prompt | [inpaint](./using-diffusers/inpaint) | +| Text-Guided Depth-to-Image Translation | adapt parts of an image guided by a text prompt while preserving structure via depth estimation | [depth2img](./using-diffusers/depth2img) | + +Start by creating an instance of a [`DiffusionPipeline`] and specify which pipeline checkpoint you would like to download. +You can use the [`DiffusionPipeline`] for any [checkpoint](https://huggingface.co/models?library=diffusers&sort=downloads) stored on the Hugging Face Hub. +In this quicktour, you'll load the [`stable-diffusion-v1-5`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) checkpoint for text-to-image generation. + + + +For [Stable Diffusion](https://huggingface.co/CompVis/stable-diffusion) models, please carefully read the [license](https://huggingface.co/spaces/CompVis/stable-diffusion-license) first before running the model. 🧨 Diffusers implements a [`safety_checker`](https://github.com/huggingface/diffusers/blob/main/src/diffusers/pipelines/stable_diffusion/safety_checker.py) to prevent offensive or harmful content, but the model's improved image generation capabilities can still produce potentially harmful content. + + + +Load the model with the [`~DiffusionPipeline.from_pretrained`] method: + +```python +>>> from diffusers import DiffusionPipeline + +>>> pipeline = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", use_safetensors=True) +``` + +The [`DiffusionPipeline`] downloads and caches all modeling, tokenization, and scheduling components. You'll see that the Stable Diffusion pipeline is composed of the [`UNet2DConditionModel`] and [`PNDMScheduler`] among other things: + +```py +>>> pipeline +StableDiffusionPipeline { + "_class_name": "StableDiffusionPipeline", + "_diffusers_version": "0.21.4", + ..., + "scheduler": [ + "diffusers", + "PNDMScheduler" + ], + ..., + "unet": [ + "diffusers", + "UNet2DConditionModel" + ], + "vae": [ + "diffusers", + "AutoencoderKL" + ] +} +``` + +We strongly recommend running the pipeline on a GPU because the model consists of roughly 1.4 billion parameters. +You can move the generator object to a GPU, just like you would in PyTorch: + +```python +>>> pipeline.to("cuda") +``` + +Now you can pass a text prompt to the `pipeline` to generate an image, and then access the denoised image. By default, the image output is wrapped in a [`PIL.Image`](https://pillow.readthedocs.io/en/stable/reference/Image.html?highlight=image#the-image-class) object. + +```python +>>> image = pipeline("An image of a squirrel in Picasso style").images[0] +>>> image +``` + +
+ +
+ +Save the image by calling `save`: + +```python +>>> image.save("image_of_squirrel_painting.png") +``` + +### Local pipeline + +You can also use the pipeline locally. The only difference is you need to download the weights first: + +```bash +!git lfs install +!git clone https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5 +``` + +Then load the saved weights into the pipeline: + +```python +>>> pipeline = DiffusionPipeline.from_pretrained("./stable-diffusion-v1-5", use_safetensors=True) +``` + +Now, you can run the pipeline as you would in the section above. + +### Swapping schedulers + +Different schedulers come with different denoising speeds and quality trade-offs. The best way to find out which one works best for you is to try them out! One of the main features of 🧨 Diffusers is to allow you to easily switch between schedulers. For example, to replace the default [`PNDMScheduler`] with the [`EulerDiscreteScheduler`], load it with the [`~diffusers.ConfigMixin.from_config`] method: + +```py +>>> from diffusers import EulerDiscreteScheduler + +>>> pipeline = DiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", use_safetensors=True) +>>> pipeline.scheduler = EulerDiscreteScheduler.from_config(pipeline.scheduler.config) +``` + +Try generating an image with the new scheduler and see if you notice a difference! + +In the next section, you'll take a closer look at the components - the model and scheduler - that make up the [`DiffusionPipeline`] and learn how to use these components to generate an image of a cat. + +## Models + +Most models take a noisy sample, and at each timestep it predicts the *noise residual* (other models learn to predict the previous sample directly or the velocity or [`v-prediction`](https://github.com/huggingface/diffusers/blob/5e5ce13e2f89ac45a0066cb3f369462a3cf1d9ef/src/diffusers/schedulers/scheduling_ddim.py#L110)), the difference between a less noisy image and the input image. You can mix and match models to create other diffusion systems. + +Models are initiated with the [`~ModelMixin.from_pretrained`] method which also locally caches the model weights so it is faster the next time you load the model. For the quicktour, you'll load the [`UNet2DModel`], a basic unconditional image generation model with a checkpoint trained on cat images: + +```py +>>> from diffusers import UNet2DModel + +>>> repo_id = "google/ddpm-cat-256" +>>> model = UNet2DModel.from_pretrained(repo_id, use_safetensors=True) +``` + +> [!TIP] +> Use the [`AutoModel`] API to automatically select a model class if you're unsure of which one to use. + +To access the model parameters, call `model.config`: + +```py +>>> model.config +``` + +The model configuration is a 🧊 frozen 🧊 dictionary, which means those parameters can't be changed after the model is created. This is intentional and ensures that the parameters used to define the model architecture at the start remain the same, while other parameters can still be adjusted during inference. + +Some of the most important parameters are: + +* `sample_size`: the height and width dimension of the input sample. +* `in_channels`: the number of input channels of the input sample. +* `down_block_types` and `up_block_types`: the type of down- and upsampling blocks used to create the UNet architecture. +* `block_out_channels`: the number of output channels of the downsampling blocks; also used in reverse order for the number of input channels of the upsampling blocks. +* `layers_per_block`: the number of ResNet blocks present in each UNet block. + +To use the model for inference, create the image shape with random Gaussian noise. It should have a `batch` axis because the model can receive multiple random noises, a `channel` axis corresponding to the number of input channels, and a `sample_size` axis for the height and width of the image: + +```py +>>> import torch + +>>> torch.manual_seed(0) + +>>> noisy_sample = torch.randn(1, model.config.in_channels, model.config.sample_size, model.config.sample_size) +>>> noisy_sample.shape +torch.Size([1, 3, 256, 256]) +``` + +For inference, pass the noisy image and a `timestep` to the model. The `timestep` indicates how noisy the input image is, with more noise at the beginning and less at the end. This helps the model determine its position in the diffusion process, whether it is closer to the start or the end. Use the `sample` method to get the model output: + +```py +>>> with torch.no_grad(): +... noisy_residual = model(sample=noisy_sample, timestep=2).sample +``` + +To generate actual examples though, you'll need a scheduler to guide the denoising process. In the next section, you'll learn how to couple a model with a scheduler. + +## Schedulers + +Schedulers manage going from a noisy sample to a less noisy sample given the model output - in this case, it is the `noisy_residual`. + + + +🧨 Diffusers is a toolbox for building diffusion systems. While the [`DiffusionPipeline`] is a convenient way to get started with a pre-built diffusion system, you can also choose your own model and scheduler components separately to build a custom diffusion system. + + + +For the quicktour, you'll instantiate the [`DDPMScheduler`] with its [`~diffusers.ConfigMixin.from_config`] method: + +```py +>>> from diffusers import DDPMScheduler + +>>> scheduler = DDPMScheduler.from_pretrained(repo_id) +>>> scheduler +DDPMScheduler { + "_class_name": "DDPMScheduler", + "_diffusers_version": "0.21.4", + "beta_end": 0.02, + "beta_schedule": "linear", + "beta_start": 0.0001, + "clip_sample": true, + "clip_sample_range": 1.0, + "dynamic_thresholding_ratio": 0.995, + "num_train_timesteps": 1000, + "prediction_type": "epsilon", + "sample_max_value": 1.0, + "steps_offset": 0, + "thresholding": false, + "timestep_spacing": "leading", + "trained_betas": null, + "variance_type": "fixed_small" +} +``` + + + +💡 Unlike a model, a scheduler does not have trainable weights and is parameter-free! + + + +Some of the most important parameters are: + +* `num_train_timesteps`: the length of the denoising process or, in other words, the number of timesteps required to process random Gaussian noise into a data sample. +* `beta_schedule`: the type of noise schedule to use for inference and training. +* `beta_start` and `beta_end`: the start and end noise values for the noise schedule. + +To predict a slightly less noisy image, pass the following to the scheduler's [`~diffusers.DDPMScheduler.step`] method: model output, `timestep`, and current `sample`. + +```py +>>> less_noisy_sample = scheduler.step(model_output=noisy_residual, timestep=2, sample=noisy_sample).prev_sample +>>> less_noisy_sample.shape +torch.Size([1, 3, 256, 256]) +``` + +The `less_noisy_sample` can be passed to the next `timestep` where it'll get even less noisy! Let's bring it all together now and visualize the entire denoising process. + +First, create a function that postprocesses and displays the denoised image as a `PIL.Image`: + +```py +>>> import PIL.Image +>>> import numpy as np + + +>>> def display_sample(sample, i): +... image_processed = sample.cpu().permute(0, 2, 3, 1) +... image_processed = (image_processed + 1.0) * 127.5 +... image_processed = image_processed.numpy().astype(np.uint8) + +... image_pil = PIL.Image.fromarray(image_processed[0]) +... display(f"Image at step {i}") +... display(image_pil) +``` + +To speed up the denoising process, move the input and model to a GPU: + +```py +>>> model.to("cuda") +>>> noisy_sample = noisy_sample.to("cuda") +``` + +Now create a denoising loop that predicts the residual of the less noisy sample, and computes the less noisy sample with the scheduler: + +```py +>>> import tqdm + +>>> sample = noisy_sample + +>>> for i, t in enumerate(tqdm.tqdm(scheduler.timesteps)): +... # 1. predict noise residual +... with torch.no_grad(): +... residual = model(sample, t).sample + +... # 2. compute less noisy image and set x_t -> x_t-1 +... sample = scheduler.step(residual, t, sample).prev_sample + +... # 3. optionally look at image +... if (i + 1) % 50 == 0: +... display_sample(sample, i + 1) +``` + +Sit back and watch as a cat is generated from nothing but noise! 😻 + +
+ +
+ +## Next steps + +Hopefully, you generated some cool images with 🧨 Diffusers in this quicktour! For your next steps, you can: + +* Train or finetune a model to generate your own images in the [training](./tutorials/basic_training) tutorial. +* See example official and community [training or finetuning scripts](https://github.com/huggingface/diffusers/tree/main/examples#-diffusers-examples) for a variety of use cases. +* Learn more about loading, accessing, changing, and comparing schedulers in the [Using different Schedulers](./using-diffusers/schedulers) guide. +* Explore prompt engineering, speed and memory optimizations, and tips and tricks for generating higher-quality images with the [Stable Diffusion](./stable_diffusion) guide. +* Dive deeper into speeding up 🧨 Diffusers with guides on [optimized PyTorch on a GPU](./optimization/fp16), and inference guides for running [Stable Diffusion on Apple Silicon (M1/M2)](./optimization/mps) and [ONNX Runtime](./optimization/onnx). diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/stable_diffusion.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/stable_diffusion.md new file mode 100644 index 0000000000000000000000000000000000000000..fc20d259f5f7f6f906440346c092edd3c1a38c3f --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/stable_diffusion.md @@ -0,0 +1,261 @@ + + +# Effective and efficient diffusion + +[[open-in-colab]] + +Getting the [`DiffusionPipeline`] to generate images in a certain style or include what you want can be tricky. Often times, you have to run the [`DiffusionPipeline`] several times before you end up with an image you're happy with. But generating something out of nothing is a computationally intensive process, especially if you're running inference over and over again. + +This is why it's important to get the most *computational* (speed) and *memory* (GPU vRAM) efficiency from the pipeline to reduce the time between inference cycles so you can iterate faster. + +This tutorial walks you through how to generate faster and better with the [`DiffusionPipeline`]. + +Begin by loading the [`stable-diffusion-v1-5/stable-diffusion-v1-5`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) model: + +```python +from diffusers import DiffusionPipeline + +model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5" +pipeline = DiffusionPipeline.from_pretrained(model_id, use_safetensors=True) +``` + +The example prompt you'll use is a portrait of an old warrior chief, but feel free to use your own prompt: + +```python +prompt = "portrait photo of a old warrior chief" +``` + +## Speed + + + +💡 If you don't have access to a GPU, you can use one for free from a GPU provider like [Colab](https://colab.research.google.com/)! + + + +One of the simplest ways to speed up inference is to place the pipeline on a GPU the same way you would with any PyTorch module: + +```python +pipeline = pipeline.to("cuda") +``` + +To make sure you can use the same image and improve on it, use a [`Generator`](https://pytorch.org/docs/stable/generated/torch.Generator.html) and set a seed for [reproducibility](./using-diffusers/reusing_seeds): + +```python +import torch + +generator = torch.Generator("cuda").manual_seed(0) +``` + +Now you can generate an image: + +```python +image = pipeline(prompt, generator=generator).images[0] +image +``` + +
+ +
+ +This process took ~30 seconds on a T4 GPU (it might be faster if your allocated GPU is better than a T4). By default, the [`DiffusionPipeline`] runs inference with full `float32` precision for 50 inference steps. You can speed this up by switching to a lower precision like `float16` or running fewer inference steps. + +Let's start by loading the model in `float16` and generate an image: + +```python +import torch + +pipeline = DiffusionPipeline.from_pretrained(model_id, torch_dtype=torch.float16, use_safetensors=True) +pipeline = pipeline.to("cuda") +generator = torch.Generator("cuda").manual_seed(0) +image = pipeline(prompt, generator=generator).images[0] +image +``` + +
+ +
+ +This time, it only took ~11 seconds to generate the image, which is almost 3x faster than before! + + + +💡 We strongly suggest always running your pipelines in `float16`, and so far, we've rarely seen any degradation in output quality. + + + +Another option is to reduce the number of inference steps. Choosing a more efficient scheduler could help decrease the number of steps without sacrificing output quality. You can find which schedulers are compatible with the current model in the [`DiffusionPipeline`] by calling the `compatibles` method: + +```python +pipeline.scheduler.compatibles +[ + diffusers.schedulers.scheduling_lms_discrete.LMSDiscreteScheduler, + diffusers.schedulers.scheduling_unipc_multistep.UniPCMultistepScheduler, + diffusers.schedulers.scheduling_k_dpm_2_discrete.KDPM2DiscreteScheduler, + diffusers.schedulers.scheduling_deis_multistep.DEISMultistepScheduler, + diffusers.schedulers.scheduling_euler_discrete.EulerDiscreteScheduler, + diffusers.schedulers.scheduling_dpmsolver_multistep.DPMSolverMultistepScheduler, + diffusers.schedulers.scheduling_ddpm.DDPMScheduler, + diffusers.schedulers.scheduling_dpmsolver_singlestep.DPMSolverSinglestepScheduler, + diffusers.schedulers.scheduling_k_dpm_2_ancestral_discrete.KDPM2AncestralDiscreteScheduler, + diffusers.utils.dummy_torch_and_torchsde_objects.DPMSolverSDEScheduler, + diffusers.schedulers.scheduling_heun_discrete.HeunDiscreteScheduler, + diffusers.schedulers.scheduling_pndm.PNDMScheduler, + diffusers.schedulers.scheduling_euler_ancestral_discrete.EulerAncestralDiscreteScheduler, + diffusers.schedulers.scheduling_ddim.DDIMScheduler, +] +``` + +The Stable Diffusion model uses the [`PNDMScheduler`] by default which usually requires ~50 inference steps, but more performant schedulers like [`DPMSolverMultistepScheduler`], require only ~20 or 25 inference steps. Use the [`~ConfigMixin.from_config`] method to load a new scheduler: + +```python +from diffusers import DPMSolverMultistepScheduler + +pipeline.scheduler = DPMSolverMultistepScheduler.from_config(pipeline.scheduler.config) +``` + +Now set the `num_inference_steps` to 20: + +```python +generator = torch.Generator("cuda").manual_seed(0) +image = pipeline(prompt, generator=generator, num_inference_steps=20).images[0] +image +``` + +
+ +
+ +Great, you've managed to cut the inference time to just 4 seconds! ⚡️ + +## Memory + +The other key to improving pipeline performance is consuming less memory, which indirectly implies more speed, since you're often trying to maximize the number of images generated per second. The easiest way to see how many images you can generate at once is to try out different batch sizes until you get an `OutOfMemoryError` (OOM). + +Create a function that'll generate a batch of images from a list of prompts and `Generators`. Make sure to assign each `Generator` a seed so you can reuse it if it produces a good result. + +```python +def get_inputs(batch_size=1): + generator = [torch.Generator("cuda").manual_seed(i) for i in range(batch_size)] + prompts = batch_size * [prompt] + num_inference_steps = 20 + + return {"prompt": prompts, "generator": generator, "num_inference_steps": num_inference_steps} +``` + +Start with `batch_size=4` and see how much memory you've consumed: + +```python +from diffusers.utils import make_image_grid + +images = pipeline(**get_inputs(batch_size=4)).images +make_image_grid(images, 2, 2) +``` + +Unless you have a GPU with more vRAM, the code above probably returned an `OOM` error! Most of the memory is taken up by the cross-attention layers. Instead of running this operation in a batch, you can run it sequentially to save a significant amount of memory. All you have to do is configure the pipeline to use the [`~DiffusionPipeline.enable_attention_slicing`] function: + +```python +pipeline.enable_attention_slicing() +``` + +Now try increasing the `batch_size` to 8! + +```python +images = pipeline(**get_inputs(batch_size=8)).images +make_image_grid(images, rows=2, cols=4) +``` + +
+ +
+ +Whereas before you couldn't even generate a batch of 4 images, now you can generate a batch of 8 images at ~3.5 seconds per image! This is probably the fastest you can go on a T4 GPU without sacrificing quality. + +## Quality + +In the last two sections, you learned how to optimize the speed of your pipeline by using `fp16`, reducing the number of inference steps by using a more performant scheduler, and enabling attention slicing to reduce memory consumption. Now you're going to focus on how to improve the quality of generated images. + +### Better checkpoints + +The most obvious step is to use better checkpoints. The Stable Diffusion model is a good starting point, and since its official launch, several improved versions have also been released. However, using a newer version doesn't automatically mean you'll get better results. You'll still have to experiment with different checkpoints yourself, and do a little research (such as using [negative prompts](https://minimaxir.com/2022/11/stable-diffusion-negative-prompt/)) to get the best results. + +As the field grows, there are more and more high-quality checkpoints finetuned to produce certain styles. Try exploring the [Hub](https://huggingface.co/models?library=diffusers&sort=downloads) and [Diffusers Gallery](https://huggingface.co/spaces/huggingface-projects/diffusers-gallery) to find one you're interested in! + +### Better pipeline components + +You can also try replacing the current pipeline components with a newer version. Let's try loading the latest [autoencoder](https://huggingface.co/stabilityai/stable-diffusion-2-1/tree/main/vae) from Stability AI into the pipeline, and generate some images: + +```python +from diffusers import AutoencoderKL + +vae = AutoencoderKL.from_pretrained("stabilityai/sd-vae-ft-mse", torch_dtype=torch.float16).to("cuda") +pipeline.vae = vae +images = pipeline(**get_inputs(batch_size=8)).images +make_image_grid(images, rows=2, cols=4) +``` + +
+ +
+ +### Better prompt engineering + +The text prompt you use to generate an image is super important, so much so that it is called *prompt engineering*. Some considerations to keep during prompt engineering are: + +- How is the image or similar images of the one I want to generate stored on the internet? +- What additional detail can I give that steers the model towards the style I want? + +With this in mind, let's improve the prompt to include color and higher quality details: + +```python +prompt += ", tribal panther make up, blue on red, side profile, looking away, serious eyes" +prompt += " 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta" +``` + +Generate a batch of images with the new prompt: + +```python +images = pipeline(**get_inputs(batch_size=8)).images +make_image_grid(images, rows=2, cols=4) +``` + +
+ +
+ +Pretty impressive! Let's tweak the second image - corresponding to the `Generator` with a seed of `1` - a bit more by adding some text about the age of the subject: + +```python +prompts = [ + "portrait photo of the oldest warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta", + "portrait photo of an old warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta", + "portrait photo of a warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta", + "portrait photo of a young warrior chief, tribal panther make up, blue on red, side profile, looking away, serious eyes 50mm portrait photography, hard rim lighting photography--beta --ar 2:3 --beta --upbeta", +] + +generator = [torch.Generator("cuda").manual_seed(1) for _ in range(len(prompts))] +images = pipeline(prompt=prompts, generator=generator, num_inference_steps=25).images +make_image_grid(images, 2, 2) +``` + +
+ +
+ +## Next steps + +In this tutorial, you learned how to optimize a [`DiffusionPipeline`] for computational and memory efficiency as well as improving the quality of generated outputs. If you're interested in making your pipeline even faster, take a look at the following resources: + +- Learn how [PyTorch 2.0](./optimization/torch2.0) and [`torch.compile`](https://pytorch.org/docs/stable/generated/torch.compile.html) can yield 5 - 300% faster inference speed. On an A100 GPU, inference can be up to 50% faster! +- If you can't use PyTorch 2, we recommend you install [xFormers](./optimization/xformers). Its memory-efficient attention mechanism works great with PyTorch 1.13.1 for faster speed and reduced memory consumption. +- Other optimization techniques, such as model offloading, are covered in [this guide](./optimization/fp16). diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/training/adapt_a_model.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/training/adapt_a_model.md new file mode 100644 index 0000000000000000000000000000000000000000..f528c8bfb65616f16967be018efaf5c36c146be3 --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/training/adapt_a_model.md @@ -0,0 +1,47 @@ +# Adapt a model to a new task + +Many diffusion systems share the same components, allowing you to adapt a pretrained model for one task to an entirely different task. + +This guide will show you how to adapt a pretrained text-to-image model for inpainting by initializing and modifying the architecture of a pretrained [`UNet2DConditionModel`]. + +## Configure UNet2DConditionModel parameters + +A [`UNet2DConditionModel`] by default accepts 4 channels in the [input sample](https://huggingface.co/docs/diffusers/v0.16.0/en/api/models#diffusers.UNet2DConditionModel.in_channels). For example, load a pretrained text-to-image model like [`stable-diffusion-v1-5/stable-diffusion-v1-5`](https://huggingface.co/stable-diffusion-v1-5/stable-diffusion-v1-5) and take a look at the number of `in_channels`: + +```py +from diffusers import StableDiffusionPipeline + +pipeline = StableDiffusionPipeline.from_pretrained("stable-diffusion-v1-5/stable-diffusion-v1-5", use_safetensors=True) +pipeline.unet.config["in_channels"] +4 +``` + +Inpainting requires 9 channels in the input sample. You can check this value in a pretrained inpainting model like [`runwayml/stable-diffusion-inpainting`](https://huggingface.co/runwayml/stable-diffusion-inpainting): + +```py +from diffusers import StableDiffusionPipeline + +pipeline = StableDiffusionPipeline.from_pretrained("runwayml/stable-diffusion-inpainting", use_safetensors=True) +pipeline.unet.config["in_channels"] +9 +``` + +To adapt your text-to-image model for inpainting, you'll need to change the number of `in_channels` from 4 to 9. + +Initialize a [`UNet2DConditionModel`] with the pretrained text-to-image model weights, and change `in_channels` to 9. Changing the number of `in_channels` means you need to set `ignore_mismatched_sizes=True` and `low_cpu_mem_usage=False` to avoid a size mismatch error because the shape is different now. + +```py +from diffusers import AutoModel + +model_id = "stable-diffusion-v1-5/stable-diffusion-v1-5" +unet = AutoModel.from_pretrained( + model_id, + subfolder="unet", + in_channels=9, + low_cpu_mem_usage=False, + ignore_mismatched_sizes=True, + use_safetensors=True, +) +``` + +The pretrained weights of the other components from the text-to-image model are initialized from their checkpoints, but the input channel weights (`conv_in.weight`) of the `unet` are randomly initialized. It is important to finetune the model for inpainting because otherwise the model returns noise. diff --git a/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/training/cogvideox.md b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/training/cogvideox.md new file mode 100644 index 0000000000000000000000000000000000000000..c2b0f9ea1b50007014a3c963601e0e8be28c7deb --- /dev/null +++ b/tasks/tasksmith-48efdcc71e7d/tests/source/docs/source/en/training/cogvideox.md @@ -0,0 +1,291 @@ + +# CogVideoX + +CogVideoX is a text-to-video generation model focused on creating more coherent videos aligned with a prompt. It achieves this using several methods. + +- a 3D variational autoencoder that compresses videos spatially and temporally, improving compression rate and video accuracy. + +- an expert transformer block to help align text and video, and a 3D full attention module for capturing and creating spatially and temporally accurate videos. + +The actual test of the video instruction dimension found that CogVideoX has good effects on consistent theme, dynamic information, consistent background, object information, smooth motion, color, scene, appearance style, and temporal style but cannot achieve good results with human action, spatial relationship, and multiple objects. + +Finetuning with Diffusers can help make up for these poor results. + +## Data Preparation + +The training scripts accepts data in two formats. + +The first format is suited for small-scale training, and the second format uses a CSV format, which is more appropriate for streaming data for large-scale training. In the future, Diffusers will support the `