}
+... """
+
+... predictions, targets = evaluation_results.predictions, evaluation_results.label_ids
+
+... # For metric computation we need to provide:
+... # - targets in a form of list of dictionaries with keys "boxes", "labels"
+... # - predictions in a form of list of dictionaries with keys "boxes", "scores", "labels"
+
+... image_sizes = []
+... post_processed_targets = []
+... post_processed_predictions = []
+
+... # Collect targets in the required format for metric computation
+... for batch in targets:
+... # collect image sizes, we will need them for predictions post processing
+... batch_image_sizes = torch.tensor(np.array([x["orig_size"] for x in batch]))
+... image_sizes.append(batch_image_sizes)
+... # collect targets in the required format for metric computation
+... # boxes were converted to YOLO format needed for model training
+... # here we will convert them to Pascal VOC format (x_min, y_min, x_max, y_max)
+... for image_target in batch:
+... boxes = torch.tensor(image_target["boxes"])
+... boxes = convert_bbox_yolo_to_pascal(boxes, image_target["orig_size"])
+... labels = torch.tensor(image_target["class_labels"])
+... post_processed_targets.append({"boxes": boxes, "labels": labels})
+
+... # Collect predictions in the required format for metric computation,
+... # model produce boxes in YOLO format, then image_processor convert them to Pascal VOC format
+... for batch, target_sizes in zip(predictions, image_sizes):
+... batch_logits, batch_boxes = batch[1], batch[2]
+... output = ModelOutput(logits=torch.tensor(batch_logits), pred_boxes=torch.tensor(batch_boxes))
+... post_processed_output = image_processor.post_process_object_detection(
+... output, threshold=threshold, target_sizes=target_sizes
+... )
+... post_processed_predictions.extend(post_processed_output)
+
+... # Compute metrics
+... metric = MeanAveragePrecision(box_format="xyxy", class_metrics=True)
+... metric.update(post_processed_predictions, post_processed_targets)
+... metrics = metric.compute()
+
+... # Replace list of per class metrics with separate metric for each class
+... classes = metrics.pop("classes")
+... map_per_class = metrics.pop("map_per_class")
+... mar_100_per_class = metrics.pop("mar_100_per_class")
+... for class_id, class_map, class_mar in zip(classes, map_per_class, mar_100_per_class):
+... class_name = id2label[class_id.item()] if id2label is not None else class_id.item()
+... metrics[f"map_{class_name}"] = class_map
+... metrics[f"mar_100_{class_name}"] = class_mar
+
+... metrics = {k: round(v.item(), 4) for k, v in metrics.items()}
+
+... return metrics
+
+
+>>> eval_compute_metrics_fn = partial(
+... compute_metrics, image_processor=image_processor, id2label=id2label, threshold=0.0
+... )
+```
+
+## Training the detection model
+
+You have done most of the heavy lifting in the previous sections, so now you are ready to train your model!
+The images in this dataset are still quite large, even after resizing. This means that finetuning this model will
+require at least one GPU.
+
+Training involves the following steps:
+1. Load the model with [`AutoModelForObjectDetection`] using the same checkpoint as in the preprocessing.
+2. Define your training hyperparameters in [`TrainingArguments`].
+3. Pass the training arguments to [`Trainer`] along with the model, dataset, image processor, and data collator.
+4. Call [`~Trainer.train`] to finetune your model.
+
+When loading the model from the same checkpoint that you used for the preprocessing, remember to pass the `label2id`
+and `id2label` maps that you created earlier from the dataset's metadata. Additionally, we specify `ignore_mismatched_sizes=True` to replace the existing classification head with a new one.
+
+```py
+>>> from transformers import AutoModelForObjectDetection
+
+>>> model = AutoModelForObjectDetection.from_pretrained(
+... MODEL_NAME,
+... id2label=id2label,
+... label2id=label2id,
+... ignore_mismatched_sizes=True,
+... )
+```
+
+In the [`TrainingArguments`] use `output_dir` to specify where to save your model, then configure hyperparameters as you see fit. For `num_train_epochs=30` training will take about 35 minutes in Google Colab T4 GPU, increase the number of epoch to get better results.
+
+Important notes:
+ - Do not remove unused columns because this will drop the image column. Without the image column, you
+can't create `pixel_values`. For this reason, set `remove_unused_columns` to `False`.
+ - Set `eval_do_concat_batches=False` to get proper evaluation results. Images have different number of target boxes, if batches are concatenated we will not be able to determine which boxes belongs to particular image.
+
+If you wish to share your model by pushing to the Hub, set `push_to_hub` to `True` (you must be signed in to Hugging
+Face to upload your model).
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(
+... output_dir="detr_finetuned_cppe5",
+... num_train_epochs=30,
+... fp16=False,
+... per_device_train_batch_size=8,
+... dataloader_num_workers=4,
+... learning_rate=5e-5,
+... lr_scheduler_type="cosine",
+... weight_decay=1e-4,
+... max_grad_norm=0.01,
+... metric_for_best_model="eval_map",
+... greater_is_better=True,
+... load_best_model_at_end=True,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... save_total_limit=2,
+... remove_unused_columns=False,
+... eval_do_concat_batches=False,
+... push_to_hub=True,
+... )
+```
+
+Finally, bring everything together, and call [`~transformers.Trainer.train`]:
+
+```py
+>>> from transformers import Trainer
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=cppe5["train"],
+... eval_dataset=cppe5["validation"],
+... processing_class=image_processor,
+... data_collator=collate_fn,
+... compute_metrics=eval_compute_metrics_fn,
+... )
+
+>>> trainer.train()
+```
+
+
+
+ [3210/3210 26:07, Epoch 30/30]
+
+
+
+ Epoch
+ Training Loss
+ Validation Loss
+ Map
+ Map 50
+ Map 75
+ Map Small
+ Map Medium
+ Map Large
+ Mar 1
+ Mar 10
+ Mar 100
+ Mar Small
+ Mar Medium
+ Mar Large
+ Map Coverall
+ Mar 100 Coverall
+ Map Face Shield
+ Mar 100 Face Shield
+ Map Gloves
+ Mar 100 Gloves
+ Map Goggles
+ Mar 100 Goggles
+ Map Mask
+ Mar 100 Mask
+
+
+
+
+ 1
+ No log
+ 2.629903
+ 0.008900
+ 0.023200
+ 0.006500
+ 0.001300
+ 0.002800
+ 0.020500
+ 0.021500
+ 0.070400
+ 0.101400
+ 0.007600
+ 0.106200
+ 0.096100
+ 0.036700
+ 0.232000
+ 0.000300
+ 0.019000
+ 0.003900
+ 0.125400
+ 0.000100
+ 0.003100
+ 0.003500
+ 0.127600
+
+
+ 2
+ No log
+ 3.479864
+ 0.014800
+ 0.034600
+ 0.010800
+ 0.008600
+ 0.011700
+ 0.012500
+ 0.041100
+ 0.098700
+ 0.130000
+ 0.056000
+ 0.062200
+ 0.111900
+ 0.053500
+ 0.447300
+ 0.010600
+ 0.100000
+ 0.000200
+ 0.022800
+ 0.000100
+ 0.015400
+ 0.009700
+ 0.064400
+
+
+ 3
+ No log
+ 2.107622
+ 0.041700
+ 0.094000
+ 0.034300
+ 0.024100
+ 0.026400
+ 0.047400
+ 0.091500
+ 0.182800
+ 0.225800
+ 0.087200
+ 0.199400
+ 0.210600
+ 0.150900
+ 0.571200
+ 0.017300
+ 0.101300
+ 0.007300
+ 0.180400
+ 0.002100
+ 0.026200
+ 0.031000
+ 0.250200
+
+
+ 4
+ No log
+ 2.031242
+ 0.055900
+ 0.120600
+ 0.046900
+ 0.013800
+ 0.038100
+ 0.090300
+ 0.105900
+ 0.225600
+ 0.266100
+ 0.130200
+ 0.228100
+ 0.330000
+ 0.191000
+ 0.572100
+ 0.010600
+ 0.157000
+ 0.014600
+ 0.235300
+ 0.001700
+ 0.052300
+ 0.061800
+ 0.313800
+
+
+ 5
+ 3.889400
+ 1.883433
+ 0.089700
+ 0.201800
+ 0.067300
+ 0.022800
+ 0.065300
+ 0.129500
+ 0.136000
+ 0.272200
+ 0.303700
+ 0.112900
+ 0.312500
+ 0.424600
+ 0.300200
+ 0.585100
+ 0.032700
+ 0.202500
+ 0.031300
+ 0.271000
+ 0.008700
+ 0.126200
+ 0.075500
+ 0.333800
+
+
+ 6
+ 3.889400
+ 1.807503
+ 0.118500
+ 0.270900
+ 0.090200
+ 0.034900
+ 0.076700
+ 0.152500
+ 0.146100
+ 0.297800
+ 0.325400
+ 0.171700
+ 0.283700
+ 0.545900
+ 0.396900
+ 0.554500
+ 0.043000
+ 0.262000
+ 0.054500
+ 0.271900
+ 0.020300
+ 0.230800
+ 0.077600
+ 0.308000
+
+
+ 7
+ 3.889400
+ 1.716169
+ 0.143500
+ 0.307700
+ 0.123200
+ 0.045800
+ 0.097800
+ 0.258300
+ 0.165300
+ 0.327700
+ 0.352600
+ 0.140900
+ 0.336700
+ 0.599400
+ 0.442900
+ 0.620700
+ 0.069400
+ 0.301300
+ 0.081600
+ 0.292000
+ 0.011000
+ 0.230800
+ 0.112700
+ 0.318200
+
+
+ 8
+ 3.889400
+ 1.679014
+ 0.153000
+ 0.355800
+ 0.127900
+ 0.038700
+ 0.115600
+ 0.291600
+ 0.176000
+ 0.322500
+ 0.349700
+ 0.135600
+ 0.326100
+ 0.643700
+ 0.431700
+ 0.582900
+ 0.069800
+ 0.265800
+ 0.088600
+ 0.274600
+ 0.028300
+ 0.280000
+ 0.146700
+ 0.345300
+
+
+ 9
+ 3.889400
+ 1.618239
+ 0.172100
+ 0.375300
+ 0.137600
+ 0.046100
+ 0.141700
+ 0.308500
+ 0.194000
+ 0.356200
+ 0.386200
+ 0.162400
+ 0.359200
+ 0.677700
+ 0.469800
+ 0.623900
+ 0.102100
+ 0.317700
+ 0.099100
+ 0.290200
+ 0.029300
+ 0.335400
+ 0.160200
+ 0.364000
+
+
+ 10
+ 1.599700
+ 1.572512
+ 0.179500
+ 0.400400
+ 0.147200
+ 0.056500
+ 0.141700
+ 0.316700
+ 0.213100
+ 0.357600
+ 0.381300
+ 0.197900
+ 0.344300
+ 0.638500
+ 0.466900
+ 0.623900
+ 0.101300
+ 0.311400
+ 0.104700
+ 0.279500
+ 0.051600
+ 0.338500
+ 0.173000
+ 0.353300
+
+
+ 11
+ 1.599700
+ 1.528889
+ 0.192200
+ 0.415000
+ 0.160800
+ 0.053700
+ 0.150500
+ 0.378000
+ 0.211500
+ 0.371700
+ 0.397800
+ 0.204900
+ 0.374600
+ 0.684800
+ 0.491900
+ 0.632400
+ 0.131200
+ 0.346800
+ 0.122000
+ 0.300900
+ 0.038400
+ 0.344600
+ 0.177500
+ 0.364400
+
+
+ 12
+ 1.599700
+ 1.517532
+ 0.198300
+ 0.429800
+ 0.159800
+ 0.066400
+ 0.162900
+ 0.383300
+ 0.220700
+ 0.382100
+ 0.405400
+ 0.214800
+ 0.383200
+ 0.672900
+ 0.469000
+ 0.610400
+ 0.167800
+ 0.379700
+ 0.119700
+ 0.307100
+ 0.038100
+ 0.335400
+ 0.196800
+ 0.394200
+
+
+ 13
+ 1.599700
+ 1.488849
+ 0.209800
+ 0.452300
+ 0.172300
+ 0.094900
+ 0.171100
+ 0.437800
+ 0.222000
+ 0.379800
+ 0.411500
+ 0.203800
+ 0.397300
+ 0.707500
+ 0.470700
+ 0.620700
+ 0.186900
+ 0.407600
+ 0.124200
+ 0.306700
+ 0.059300
+ 0.355400
+ 0.207700
+ 0.367100
+
+
+ 14
+ 1.599700
+ 1.482210
+ 0.228900
+ 0.482600
+ 0.187800
+ 0.083600
+ 0.191800
+ 0.444100
+ 0.225900
+ 0.376900
+ 0.407400
+ 0.182500
+ 0.384800
+ 0.700600
+ 0.512100
+ 0.640100
+ 0.175000
+ 0.363300
+ 0.144300
+ 0.300000
+ 0.083100
+ 0.363100
+ 0.229900
+ 0.370700
+
+
+ 15
+ 1.326800
+ 1.475198
+ 0.216300
+ 0.455600
+ 0.174900
+ 0.088500
+ 0.183500
+ 0.424400
+ 0.226900
+ 0.373400
+ 0.404300
+ 0.199200
+ 0.396400
+ 0.677800
+ 0.496300
+ 0.633800
+ 0.166300
+ 0.392400
+ 0.128900
+ 0.312900
+ 0.085200
+ 0.312300
+ 0.205000
+ 0.370200
+
+
+ 16
+ 1.326800
+ 1.459697
+ 0.233200
+ 0.504200
+ 0.192200
+ 0.096000
+ 0.202000
+ 0.430800
+ 0.239100
+ 0.382400
+ 0.412600
+ 0.219500
+ 0.403100
+ 0.670400
+ 0.485200
+ 0.625200
+ 0.196500
+ 0.410100
+ 0.135700
+ 0.299600
+ 0.123100
+ 0.356900
+ 0.225300
+ 0.371100
+
+
+ 17
+ 1.326800
+ 1.407340
+ 0.243400
+ 0.511900
+ 0.204500
+ 0.121000
+ 0.215700
+ 0.468000
+ 0.246200
+ 0.394600
+ 0.424200
+ 0.225900
+ 0.416100
+ 0.705200
+ 0.494900
+ 0.638300
+ 0.224900
+ 0.430400
+ 0.157200
+ 0.317900
+ 0.115700
+ 0.369200
+ 0.224200
+ 0.365300
+
+
+ 18
+ 1.326800
+ 1.419522
+ 0.245100
+ 0.521500
+ 0.210000
+ 0.116100
+ 0.211500
+ 0.489900
+ 0.255400
+ 0.391600
+ 0.419700
+ 0.198800
+ 0.421200
+ 0.701400
+ 0.501800
+ 0.634200
+ 0.226700
+ 0.410100
+ 0.154400
+ 0.321400
+ 0.105900
+ 0.352300
+ 0.236700
+ 0.380400
+
+
+ 19
+ 1.158600
+ 1.398764
+ 0.253600
+ 0.519200
+ 0.213600
+ 0.135200
+ 0.207700
+ 0.491900
+ 0.257300
+ 0.397300
+ 0.428000
+ 0.241400
+ 0.401800
+ 0.703500
+ 0.509700
+ 0.631100
+ 0.236700
+ 0.441800
+ 0.155900
+ 0.330800
+ 0.128100
+ 0.352300
+ 0.237500
+ 0.384000
+
+
+ 20
+ 1.158600
+ 1.390591
+ 0.248800
+ 0.520200
+ 0.216600
+ 0.127500
+ 0.211400
+ 0.471900
+ 0.258300
+ 0.407000
+ 0.429100
+ 0.240300
+ 0.407600
+ 0.708500
+ 0.505800
+ 0.623400
+ 0.235500
+ 0.431600
+ 0.150000
+ 0.325000
+ 0.125700
+ 0.375400
+ 0.227200
+ 0.390200
+
+
+ 21
+ 1.158600
+ 1.360608
+ 0.262700
+ 0.544800
+ 0.222100
+ 0.134700
+ 0.230000
+ 0.487500
+ 0.269500
+ 0.413300
+ 0.436300
+ 0.236200
+ 0.419100
+ 0.709300
+ 0.514100
+ 0.637400
+ 0.257200
+ 0.450600
+ 0.165100
+ 0.338400
+ 0.139400
+ 0.372300
+ 0.237700
+ 0.382700
+
+
+ 22
+ 1.158600
+ 1.368296
+ 0.262800
+ 0.542400
+ 0.236400
+ 0.137400
+ 0.228100
+ 0.498500
+ 0.266500
+ 0.409000
+ 0.433000
+ 0.239900
+ 0.418500
+ 0.697500
+ 0.520500
+ 0.641000
+ 0.257500
+ 0.455700
+ 0.162600
+ 0.334800
+ 0.140200
+ 0.353800
+ 0.233200
+ 0.379600
+
+
+ 23
+ 1.158600
+ 1.368176
+ 0.264800
+ 0.541100
+ 0.233100
+ 0.138200
+ 0.223900
+ 0.498700
+ 0.272300
+ 0.407400
+ 0.434400
+ 0.233100
+ 0.418300
+ 0.702000
+ 0.524400
+ 0.642300
+ 0.262300
+ 0.444300
+ 0.159700
+ 0.335300
+ 0.140500
+ 0.366200
+ 0.236900
+ 0.384000
+
+
+ 24
+ 1.049700
+ 1.355271
+ 0.269700
+ 0.549200
+ 0.239100
+ 0.134700
+ 0.229900
+ 0.519200
+ 0.274800
+ 0.412700
+ 0.437600
+ 0.245400
+ 0.417200
+ 0.711200
+ 0.523200
+ 0.644100
+ 0.272100
+ 0.440500
+ 0.166700
+ 0.341500
+ 0.137700
+ 0.373800
+ 0.249000
+ 0.388000
+
+
+ 25
+ 1.049700
+ 1.355180
+ 0.272500
+ 0.547900
+ 0.243800
+ 0.149700
+ 0.229900
+ 0.523100
+ 0.272500
+ 0.415700
+ 0.442200
+ 0.256200
+ 0.420200
+ 0.705800
+ 0.523900
+ 0.639600
+ 0.271700
+ 0.451900
+ 0.166300
+ 0.346900
+ 0.153700
+ 0.383100
+ 0.247000
+ 0.389300
+
+
+ 26
+ 1.049700
+ 1.349337
+ 0.275600
+ 0.556300
+ 0.246400
+ 0.146700
+ 0.234800
+ 0.516300
+ 0.274200
+ 0.418300
+ 0.440900
+ 0.248700
+ 0.418900
+ 0.705800
+ 0.523200
+ 0.636500
+ 0.274700
+ 0.440500
+ 0.172400
+ 0.349100
+ 0.155600
+ 0.384600
+ 0.252300
+ 0.393800
+
+
+ 27
+ 1.049700
+ 1.350782
+ 0.275200
+ 0.548700
+ 0.246800
+ 0.147300
+ 0.236400
+ 0.527200
+ 0.280100
+ 0.416200
+ 0.442600
+ 0.253400
+ 0.424000
+ 0.710300
+ 0.526600
+ 0.640100
+ 0.273200
+ 0.445600
+ 0.167000
+ 0.346900
+ 0.160100
+ 0.387700
+ 0.249200
+ 0.392900
+
+
+ 28
+ 1.049700
+ 1.346533
+ 0.277000
+ 0.552800
+ 0.252900
+ 0.147400
+ 0.240000
+ 0.527600
+ 0.280900
+ 0.420900
+ 0.444100
+ 0.255500
+ 0.424500
+ 0.711200
+ 0.530200
+ 0.646800
+ 0.277400
+ 0.441800
+ 0.170900
+ 0.346900
+ 0.156600
+ 0.389200
+ 0.249600
+ 0.396000
+
+
+ 29
+ 0.993700
+ 1.346575
+ 0.277100
+ 0.554800
+ 0.252900
+ 0.148400
+ 0.239700
+ 0.523600
+ 0.278400
+ 0.420000
+ 0.443300
+ 0.256300
+ 0.424000
+ 0.705600
+ 0.529600
+ 0.647300
+ 0.273900
+ 0.439200
+ 0.174300
+ 0.348700
+ 0.157600
+ 0.386200
+ 0.250100
+ 0.395100
+
+
+ 30
+ 0.993700
+ 1.346446
+ 0.277400
+ 0.554700
+ 0.252700
+ 0.147900
+ 0.240800
+ 0.523600
+ 0.278800
+ 0.420400
+ 0.443300
+ 0.256100
+ 0.424200
+ 0.705500
+ 0.530100
+ 0.646800
+ 0.275600
+ 0.440500
+ 0.174500
+ 0.348700
+ 0.157300
+ 0.386200
+ 0.249200
+ 0.394200
+
+
+
+
+If you have set `push_to_hub` to `True` in the `training_args`, the training checkpoints are pushed to the
+Hugging Face Hub. Upon training completion, push the final model to the Hub as well by calling the [`~transformers.Trainer.push_to_hub`] method.
+
+```py
+>>> trainer.push_to_hub()
+```
+
+## Evaluate
+
+```py
+>>> from pprint import pprint
+
+>>> metrics = trainer.evaluate(eval_dataset=cppe5["test"], metric_key_prefix="test")
+>>> pprint(metrics)
+{'epoch': 30.0,
+ 'test_loss': 1.0877351760864258,
+ 'test_map': 0.4116,
+ 'test_map_50': 0.741,
+ 'test_map_75': 0.3663,
+ 'test_map_Coverall': 0.5937,
+ 'test_map_Face_Shield': 0.5863,
+ 'test_map_Gloves': 0.3416,
+ 'test_map_Goggles': 0.1468,
+ 'test_map_Mask': 0.3894,
+ 'test_map_large': 0.5637,
+ 'test_map_medium': 0.3257,
+ 'test_map_small': 0.3589,
+ 'test_mar_1': 0.323,
+ 'test_mar_10': 0.5237,
+ 'test_mar_100': 0.5587,
+ 'test_mar_100_Coverall': 0.6756,
+ 'test_mar_100_Face_Shield': 0.7294,
+ 'test_mar_100_Gloves': 0.4721,
+ 'test_mar_100_Goggles': 0.4125,
+ 'test_mar_100_Mask': 0.5038,
+ 'test_mar_large': 0.7283,
+ 'test_mar_medium': 0.4901,
+ 'test_mar_small': 0.4469,
+ 'test_runtime': 1.6526,
+ 'test_samples_per_second': 17.548,
+ 'test_steps_per_second': 2.42}
+```
+
+These results can be further improved by adjusting the hyperparameters in [`TrainingArguments`]. Give it a go!
+
+## Inference
+
+Now that you have finetuned a model, evaluated it, and uploaded it to the Hugging Face Hub, you can use it for inference.
+
+```py
+>>> import torch
+>>> import requests
+
+>>> from PIL import Image, ImageDraw
+>>> from transformers import AutoImageProcessor, AutoModelForObjectDetection
+
+>>> url = "https://images.pexels.com/photos/8413299/pexels-photo-8413299.jpeg?auto=compress&cs=tinysrgb&w=630&h=375&dpr=2"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+```
+
+Load model and image processor from the Hugging Face Hub (skip to use already trained in this session):
+```py
+>>> from accelerate.test_utils.testing import get_backend
+# automatically detects the underlying device type (CUDA, CPU, XPU, MPS, etc.)
+>>> device, _, _ = get_backend()
+>>> model_repo = "qubvel-hf/detr_finetuned_cppe5"
+
+>>> image_processor = AutoImageProcessor.from_pretrained(model_repo)
+>>> model = AutoModelForObjectDetection.from_pretrained(model_repo)
+>>> model = model.to(device)
+```
+
+And detect bounding boxes:
+
+```py
+
+>>> with torch.no_grad():
+... inputs = image_processor(images=[image], return_tensors="pt")
+... outputs = model(**inputs.to(device))
+... target_sizes = torch.tensor([[image.size[1], image.size[0]]])
+... results = image_processor.post_process_object_detection(outputs, threshold=0.3, target_sizes=target_sizes)[0]
+
+>>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+... box = [round(i, 2) for i in box.tolist()]
+... print(
+... f"Detected {model.config.id2label[label.item()]} with confidence "
+... f"{round(score.item(), 3)} at location {box}"
+... )
+Detected Gloves with confidence 0.683 at location [244.58, 124.33, 300.35, 185.13]
+Detected Mask with confidence 0.517 at location [143.73, 64.58, 219.57, 125.89]
+Detected Gloves with confidence 0.425 at location [179.15, 155.57, 262.4, 226.35]
+Detected Coverall with confidence 0.407 at location [307.13, -1.18, 477.82, 318.06]
+Detected Coverall with confidence 0.391 at location [68.61, 126.66, 309.03, 318.89]
+```
+
+Let's plot the result:
+
+```py
+>>> draw = ImageDraw.Draw(image)
+
+>>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+... box = [round(i, 2) for i in box.tolist()]
+... x, y, x2, y2 = tuple(box)
+... draw.rectangle((x, y, x2, y2), outline="red", width=1)
+... draw.text((x, y), model.config.id2label[label.item()], fill="white")
+
+>>> image
+```
+
+
+
+
+
+Prompt engineering is only a part of the LLM output optimization process. Another essential component is choosing the
+optimal text generation strategy. You can customize how your LLM selects each of the subsequent tokens when generating
+the text without modifying any of the trainable parameters. By tweaking the text generation parameters, you can reduce
+repetition in the generated text and make it more coherent and human-sounding.
+Text generation strategies and parameters are out of scope for this guide, but you can learn more about these topics in
+the following guides:
+
+* [Generation with LLMs](../llm_tutorial)
+* [Text generation strategies](../generation_strategies)
+
+
+
+## Basics of prompting
+
+### Types of models
+
+The majority of modern LLMs are decoder-only transformers. Some examples include: [LLaMA](../model_doc/llama),
+[Llama2](../model_doc/llama2), [Falcon](../model_doc/falcon), [GPT2](../model_doc/gpt2). However, you may encounter
+encoder-decoder transformer LLMs as well, for instance, [Flan-T5](../model_doc/flan-t5) and [BART](../model_doc/bart).
+
+Encoder-decoder-style models are typically used in generative tasks where the output **heavily** relies on the input, for
+example, in translation and summarization. The decoder-only models are used for all other types of generative tasks.
+
+When using a pipeline to generate text with an LLM, it's important to know what type of LLM you are using, because
+they use different pipelines.
+
+Run inference with decoder-only models with the `text-generation` pipeline:
+
+```python
+>>> from transformers import pipeline
+>>> import torch
+
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+
+>>> generator = pipeline('text-generation', model = 'openai-community/gpt2')
+>>> prompt = "Hello, I'm a language model"
+
+>>> generator(prompt, max_length = 30)
+[{'generated_text': "Hello, I'm a language model programmer so you can use some of my stuff. But you also need some sort of a C program to run."}]
+```
+
+To run inference with an encoder-decoder, use the `text2text-generation` pipeline:
+
+```python
+>>> text2text_generator = pipeline("text2text-generation", model = 'google/flan-t5-base')
+>>> prompt = "Translate from English to French: I'm very happy to see you"
+
+>>> text2text_generator(prompt)
+[{'generated_text': 'Je suis très heureuse de vous rencontrer.'}]
+```
+
+### Base vs instruct/chat models
+
+Most of the recent LLM checkpoints available on 🤗 Hub come in two versions: base and instruct (or chat). For example,
+[`tiiuae/falcon-7b`](https://huggingface.co/tiiuae/falcon-7b) and [`tiiuae/falcon-7b-instruct`](https://huggingface.co/tiiuae/falcon-7b-instruct).
+
+Base models are excellent at completing the text when given an initial prompt, however, they are not ideal for NLP tasks
+where they need to follow instructions, or for conversational use. This is where the instruct (chat) versions come in.
+These checkpoints are the result of further fine-tuning of the pre-trained base versions on instructions and conversational data.
+This additional fine-tuning makes them a better choice for many NLP tasks.
+
+Let's illustrate some simple prompts that you can use with [`tiiuae/falcon-7b-instruct`](https://huggingface.co/tiiuae/falcon-7b-instruct)
+to solve some common NLP tasks.
+
+### NLP tasks
+
+First, let's set up the environment:
+
+```bash
+pip install -q transformers accelerate
+```
+
+Next, let's load the model with the appropriate pipeline (`"text-generation"`):
+
+```python
+>>> from transformers import pipeline, AutoTokenizer
+>>> import torch
+
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+>>> model = "tiiuae/falcon-7b-instruct"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(model)
+>>> pipe = pipeline(
+... "text-generation",
+... model=model,
+... tokenizer=tokenizer,
+... torch_dtype=torch.bfloat16,
+... device_map="auto",
+... )
+```
+
+
+
+Note that Falcon models were trained using the `bfloat16` datatype, so we recommend you use the same. This requires a recent
+version of CUDA and works best on modern cards.
+
+
+
+Now that we have the model loaded via the pipeline, let's explore how you can use prompts to solve NLP tasks.
+
+#### Text classification
+
+One of the most common forms of text classification is sentiment analysis, which assigns a label like "positive", "negative",
+or "neutral" to a sequence of text. Let's write a prompt that instructs the model to classify a given text (a movie review).
+We'll start by giving the instruction, and then specifying the text to classify. Note that instead of leaving it at that, we're
+also adding the beginning of the response - `"Sentiment: "`:
+
+```python
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+>>> prompt = """Classify the text into neutral, negative or positive.
+... Text: This movie is definitely one of my favorite movies of its kind. The interaction between respectable and morally strong characters is an ode to chivalry and the honor code amongst thieves and policemen.
+... Sentiment:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=10,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result: Classify the text into neutral, negative or positive.
+Text: This movie is definitely one of my favorite movies of its kind. The interaction between respectable and morally strong characters is an ode to chivalry and the honor code amongst thieves and policemen.
+Sentiment:
+Positive
+```
+
+As a result, the output contains a classification label from the list we have provided in the instructions, and it is a correct one!
+
+
+
+You may notice that in addition to the prompt, we pass a `max_new_tokens` parameter. It controls the number of tokens the
+model shall generate, and it is one of the many text generation parameters that you can learn about
+in [Text generation strategies](../generation_strategies) guide.
+
+
+
+#### Named Entity Recognition
+
+Named Entity Recognition (NER) is a task of finding named entities in a piece of text, such as a person, location, or organization.
+Let's modify the instructions in the prompt to make the LLM perform this task. Here, let's also set `return_full_text = False`
+so that output doesn't contain the prompt:
+
+```python
+>>> torch.manual_seed(1) # doctest: +IGNORE_RESULT
+>>> prompt = """Return a list of named entities in the text.
+... Text: The Golden State Warriors are an American professional basketball team based in San Francisco.
+... Named entities:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=15,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"{seq['generated_text']}")
+- Golden State Warriors
+- San Francisco
+```
+
+As you can see, the model correctly identified two named entities from the given text.
+
+#### Translation
+
+Another task LLMs can perform is translation. You can choose to use encoder-decoder models for this task, however, here,
+for the simplicity of the examples, we'll keep using Falcon-7b-instruct, which does a decent job. Once again, here's how
+you can write a basic prompt to instruct a model to translate a piece of text from English to Italian:
+
+```python
+>>> torch.manual_seed(2) # doctest: +IGNORE_RESULT
+>>> prompt = """Translate the English text to Italian.
+... Text: Sometimes, I've believed as many as six impossible things before breakfast.
+... Translation:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=20,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"{seq['generated_text']}")
+A volte, ho creduto a sei impossibili cose prima di colazione.
+```
+
+Here we've added a `do_sample=True` and `top_k=10` to allow the model to be a bit more flexible when generating output.
+
+#### Text summarization
+
+Similar to the translation, text summarization is another generative task where the output **heavily** relies on the input,
+and encoder-decoder models can be a better choice. However, decoder-style models can be used for this task as well.
+Previously, we have placed the instructions at the very beginning of the prompt. However, the very end of the prompt can
+also be a suitable location for instructions. Typically, it's better to place the instruction on one of the extreme ends.
+
+```python
+>>> torch.manual_seed(3) # doctest: +IGNORE_RESULT
+>>> prompt = """Permaculture is a design process mimicking the diversity, functionality and resilience of natural ecosystems. The principles and practices are drawn from traditional ecological knowledge of indigenous cultures combined with modern scientific understanding and technological innovations. Permaculture design provides a framework helping individuals and communities develop innovative, creative and effective strategies for meeting basic needs while preparing for and mitigating the projected impacts of climate change.
+... Write a summary of the above text.
+... Summary:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=30,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"{seq['generated_text']}")
+Permaculture is an ecological design mimicking natural ecosystems to meet basic needs and prepare for climate change. It is based on traditional knowledge and scientific understanding.
+```
+
+#### Question answering
+
+For question answering task we can structure the prompt into the following logical components: instructions, context, question, and
+the leading word or phrase (`"Answer:"`) to nudge the model to start generating the answer:
+
+```python
+>>> torch.manual_seed(4) # doctest: +IGNORE_RESULT
+>>> prompt = """Answer the question using the context below.
+... Context: Gazpacho is a cold soup and drink made of raw, blended vegetables. Most gazpacho includes stale bread, tomato, cucumbers, onion, bell peppers, garlic, olive oil, wine vinegar, water, and salt. Northern recipes often include cumin and/or pimentón (smoked sweet paprika). Traditionally, gazpacho was made by pounding the vegetables in a mortar with a pestle; this more laborious method is still sometimes used as it helps keep the gazpacho cool and avoids the foam and silky consistency of smoothie versions made in blenders or food processors.
+... Question: What modern tool is used to make gazpacho?
+... Answer:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=10,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result: Modern tools often used to make gazpacho include
+```
+
+#### Reasoning
+
+Reasoning is one of the most difficult tasks for LLMs, and achieving good results often requires applying advanced prompting techniques, like
+[Chain-of-thought](#chain-of-thought).
+
+Let's try if we can make a model reason about a simple arithmetics task with a basic prompt:
+
+```python
+>>> torch.manual_seed(5) # doctest: +IGNORE_RESULT
+>>> prompt = """There are 5 groups of students in the class. Each group has 4 students. How many students are there in the class?"""
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=30,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result:
+There are a total of 5 groups, so there are 5 x 4=20 students in the class.
+```
+
+Correct! Let's increase the complexity a little and see if we can still get away with a basic prompt:
+
+```python
+>>> torch.manual_seed(6) # doctest: +IGNORE_RESULT
+>>> prompt = """I baked 15 muffins. I ate 2 muffins and gave 5 muffins to a neighbor. My partner then bought 6 more muffins and ate 2. How many muffins do we now have?"""
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=10,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result:
+The total number of muffins now is 21
+```
+
+This is a wrong answer, it should be 12. In this case, this can be due to the prompt being too basic, or due to the choice
+of model, after all we've picked the smallest version of Falcon. Reasoning is difficult for models of all sizes, but larger
+models are likely to perform better.
+
+## Best practices of LLM prompting
+
+In this section of the guide we have compiled a list of best practices that tend to improve the prompt results:
+
+* When choosing the model to work with, the latest and most capable models are likely to perform better.
+* Start with a simple and short prompt, and iterate from there.
+* Put the instructions at the beginning of the prompt, or at the very end. When working with large context, models apply various optimizations to prevent Attention complexity from scaling quadratically. This may make a model more attentive to the beginning or end of a prompt than the middle.
+* Clearly separate instructions from the text they apply to - more on this in the next section.
+* Be specific and descriptive about the task and the desired outcome - its format, length, style, language, etc.
+* Avoid ambiguous descriptions and instructions.
+* Favor instructions that say "what to do" instead of those that say "what not to do".
+* "Lead" the output in the right direction by writing the first word (or even begin the first sentence for the model).
+* Use advanced techniques like [Few-shot prompting](#few-shot-prompting) and [Chain-of-thought](#chain-of-thought)
+* Test your prompts with different models to assess their robustness.
+* Version and track the performance of your prompts.
+
+## Advanced prompting techniques
+
+### Few-shot prompting
+
+The basic prompts in the sections above are the examples of "zero-shot" prompts, meaning, the model has been given
+instructions and context, but no examples with solutions. LLMs that have been fine-tuned on instruction datasets, generally
+perform well on such "zero-shot" tasks. However, you may find that your task has more complexity or nuance, and, perhaps,
+you have some requirements for the output that the model doesn't catch on just from the instructions. In this case, you can
+try the technique called few-shot prompting.
+
+In few-shot prompting, we provide examples in the prompt giving the model more context to improve the performance.
+The examples condition the model to generate the output following the patterns in the examples.
+
+Here's an example:
+
+```python
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+>>> prompt = """Text: The first human went into space and orbited the Earth on April 12, 1961.
+... Date: 04/12/1961
+... Text: The first-ever televised presidential debate in the United States took place on September 28, 1960, between presidential candidates John F. Kennedy and Richard Nixon.
+... Date:"""
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=8,
+... do_sample=True,
+... top_k=10,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result: Text: The first human went into space and orbited the Earth on April 12, 1961.
+Date: 04/12/1961
+Text: The first-ever televised presidential debate in the United States took place on September 28, 1960, between presidential candidates John F. Kennedy and Richard Nixon.
+Date: 09/28/1960
+```
+
+In the above code snippet we used a single example to demonstrate the desired output to the model, so this can be called a
+"one-shot" prompting. However, depending on the task complexity you may need to use more than one example.
+
+Limitations of the few-shot prompting technique:
+- While LLMs can pick up on the patterns in the examples, these technique doesn't work well on complex reasoning tasks
+- Few-shot prompting requires creating lengthy prompts. Prompts with large number of tokens can increase computation and latency. There's also a limit to the length of the prompts.
+- Sometimes when given a number of examples, models can learn patterns that you didn't intend them to learn, e.g. that the third movie review is always negative.
+
+### Chain-of-thought
+
+Chain-of-thought (CoT) prompting is a technique that nudges a model to produce intermediate reasoning steps thus improving
+the results on complex reasoning tasks.
+
+There are two ways of steering a model to producing the reasoning steps:
+- few-shot prompting by illustrating examples with detailed answers to questions, showing the model how to work through a problem.
+- by instructing the model to reason by adding phrases like "Let's think step by step" or "Take a deep breath and work through the problem step by step."
+
+If we apply the CoT technique to the muffins example from the [reasoning section](#reasoning) and use a larger model,
+such as (`tiiuae/falcon-180B-chat`) which you can play with in the [HuggingChat](https://huggingface.co/chat/),
+we'll get a significant improvement on the reasoning result:
+
+```text
+Let's go through this step-by-step:
+1. You start with 15 muffins.
+2. You eat 2 muffins, leaving you with 13 muffins.
+3. You give 5 muffins to your neighbor, leaving you with 8 muffins.
+4. Your partner buys 6 more muffins, bringing the total number of muffins to 14.
+5. Your partner eats 2 muffins, leaving you with 12 muffins.
+Therefore, you now have 12 muffins.
+```
+
+## Prompting vs fine-tuning
+
+You can achieve great results by optimizing your prompts, however, you may still ponder whether fine-tuning a model
+would work better for your case. Here are some scenarios when fine-tuning a smaller model may be a preferred option:
+
+- Your domain is wildly different from what LLMs were pre-trained on and extensive prompt optimization did not yield sufficient results.
+- You need your model to work well in a low-resource language.
+- You need the model to be trained on sensitive data that is under strict regulations.
+- You have to use a small model due to cost, privacy, infrastructure or other limitations.
+
+In all of the above examples, you will need to make sure that you either already have or can easily obtain a large enough
+domain-specific dataset at a reasonable cost to fine-tune a model. You will also need to have enough time and resources
+to fine-tune a model.
+
+If the above examples are not the case for you, optimizing prompts can prove to be more beneficial.
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/question_answering.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/question_answering.md
new file mode 100644
index 0000000000000000000000000000000000000000..41d7fd48cf816e099892c7bfa3037825721f97eb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/question_answering.md
@@ -0,0 +1,427 @@
+
+
+# Question answering
+
+[[open-in-colab]]
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/question-answering)
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+We encourage you to login to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load SQuAD dataset
+
+Start by loading a smaller subset of the SQuAD dataset from the 🤗 Datasets library. This'll give you a chance to experiment and make sure everything works before spending more time training on the full dataset.
+
+```py
+>>> from datasets import load_dataset
+
+>>> squad = load_dataset("squad", split="train[:5000]")
+```
+
+Split the dataset's `train` split into a train and test set with the [`~datasets.Dataset.train_test_split`] method:
+
+```py
+>>> squad = squad.train_test_split(test_size=0.2)
+```
+
+Then take a look at an example:
+
+```py
+>>> squad["train"][0]
+{'answers': {'answer_start': [515], 'text': ['Saint Bernadette Soubirous']},
+ 'context': 'Architecturally, the school has a Catholic character. Atop the Main Building\'s gold dome is a golden statue of the Virgin Mary. Immediately in front of the Main Building and facing it, is a copper statue of Christ with arms upraised with the legend "Venite Ad Me Omnes". Next to the Main Building is the Basilica of the Sacred Heart. Immediately behind the basilica is the Grotto, a Marian place of prayer and reflection. It is a replica of the grotto at Lourdes, France where the Virgin Mary reputedly appeared to Saint Bernadette Soubirous in 1858. At the end of the main drive (and in a direct line that connects through 3 statues and the Gold Dome), is a simple, modern stone statue of Mary.',
+ 'id': '5733be284776f41900661182',
+ 'question': 'To whom did the Virgin Mary allegedly appear in 1858 in Lourdes France?',
+ 'title': 'University_of_Notre_Dame'
+}
+```
+
+There are several important fields here:
+
+- `answers`: the starting location of the answer token and the answer text.
+- `context`: background information from which the model needs to extract the answer.
+- `question`: the question a model should answer.
+
+## Preprocess
+
+
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+```
+
+
+
+## Train
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load DistilBERT with [`AutoModelForQuestionAnswering`]:
+
+```py
+>>> from transformers import AutoModelForQuestionAnswering, TrainingArguments, Trainer
+
+>>> model = AutoModelForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model).
+2. Pass the training arguments to [`Trainer`] along with the model, dataset, tokenizer, and data collator.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_qa_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_squad["train"],
+... eval_dataset=tokenized_squad["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+If you aren't familiar with finetuning a model with Keras, take a look at the basic tutorial [here](../training#train-a-tensorflow-model-with-keras)!
+
+
+To finetune a model in TensorFlow, start by setting up an optimizer function, learning rate schedule, and some training hyperparameters:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_epochs = 2
+>>> total_train_steps = (len(tokenized_squad["train"]) // batch_size) * num_epochs
+>>> optimizer, schedule = create_optimizer(
+... init_lr=2e-5,
+... num_warmup_steps=0,
+... num_train_steps=total_train_steps,
+... )
+```
+
+Then you can load DistilBERT with [`TFAutoModelForQuestionAnswering`]:
+
+```py
+>>> from transformers import TFAutoModelForQuestionAnswering
+
+>>> model = TFAutoModelForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Convert your datasets to the `tf.data.Dataset` format with [`~transformers.TFPreTrainedModel.prepare_tf_dataset`]:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_squad["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_squad["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+Configure the model for training with [`compile`](https://keras.io/api/models/model_training_apis/#compile-method):
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+The last thing to setup before you start training is to provide a way to push your model to the Hub. This can be done by specifying where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_qa_model",
+... tokenizer=tokenizer,
+... )
+```
+
+Finally, you're ready to start training your model! Call [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) with your training and validation datasets, the number of epochs, and your callback to finetune the model:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=[callback])
+```
+Once training is completed, your model is automatically uploaded to the Hub so everyone can use it!
+
+
+
+
+
+For a more in-depth example of how to finetune a model for question answering, take a look at the corresponding
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb)
+or [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering-tf.ipynb).
+
+
+
+## Evaluate
+
+Evaluation for question answering requires a significant amount of postprocessing. To avoid taking up too much of your time, this guide skips the evaluation step. The [`Trainer`] still calculates the evaluation loss during training so you're not completely in the dark about your model's performance.
+
+If you have more time and you're interested in how to evaluate your model for question answering, take a look at the [Question answering](https://huggingface.co/course/chapter7/7?fw=pt#post-processing) chapter from the 🤗 Hugging Face Course!
+
+## Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Come up with a question and some context you'd like the model to predict:
+
+```py
+>>> question = "How many programming languages does BLOOM support?"
+>>> context = "BLOOM has 176 billion parameters and can generate text in 46 languages natural languages and 13 programming languages."
+```
+
+The simplest way to try out your finetuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for question answering with your model, and pass your text to it:
+
+```py
+>>> from transformers import pipeline
+
+>>> question_answerer = pipeline("question-answering", model="my_awesome_qa_model")
+>>> question_answerer(question=question, context=context)
+{'score': 0.2058267742395401,
+ 'start': 10,
+ 'end': 95,
+ 'answer': '176 billion parameters and can generate text in 46 languages natural languages and 13'}
+```
+
+You can also manually replicate the results of the `pipeline` if you'd like:
+
+
+
+Tokenize the text and return PyTorch tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_qa_model")
+>>> inputs = tokenizer(question, context, return_tensors="pt")
+```
+
+Pass your inputs to the model and return the `logits`:
+
+```py
+>>> import torch
+>>> from transformers import AutoModelForQuestionAnswering
+
+>>> model = AutoModelForQuestionAnswering.from_pretrained("my_awesome_qa_model")
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+```
+
+Get the highest probability from the model output for the start and end positions:
+
+```py
+>>> answer_start_index = outputs.start_logits.argmax()
+>>> answer_end_index = outputs.end_logits.argmax()
+```
+
+Decode the predicted tokens to get the answer:
+
+```py
+>>> predict_answer_tokens = inputs.input_ids[0, answer_start_index : answer_end_index + 1]
+>>> tokenizer.decode(predict_answer_tokens)
+'176 billion parameters and can generate text in 46 languages natural languages and 13'
+```
+
+
+Tokenize the text and return TensorFlow tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_qa_model")
+>>> inputs = tokenizer(question, context, return_tensors="tf")
+```
+
+Pass your inputs to the model and return the `logits`:
+
+```py
+>>> from transformers import TFAutoModelForQuestionAnswering
+
+>>> model = TFAutoModelForQuestionAnswering.from_pretrained("my_awesome_qa_model")
+>>> outputs = model(**inputs)
+```
+
+Get the highest probability from the model output for the start and end positions:
+
+```py
+>>> answer_start_index = int(tf.math.argmax(outputs.start_logits, axis=-1)[0])
+>>> answer_end_index = int(tf.math.argmax(outputs.end_logits, axis=-1)[0])
+```
+
+Decode the predicted tokens to get the answer:
+
+```py
+>>> predict_answer_tokens = inputs.input_ids[0, answer_start_index : answer_end_index + 1]
+>>> tokenizer.decode(predict_answer_tokens)
+'176 billion parameters and can generate text in 46 languages natural languages and 13'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/semantic_segmentation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/semantic_segmentation.md
new file mode 100644
index 0000000000000000000000000000000000000000..a21ff62edf1a563f5fbdeeb5c2d55ca81d8cbf72
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/semantic_segmentation.md
@@ -0,0 +1,939 @@
+
+
+# Image Segmentation
+
+[[open-in-colab]]
+
+
+
+
},
+ {'score': None,
+ 'label': 'sidewalk',
+ 'mask': },
+ {'score': None,
+ 'label': 'building',
+ 'mask': },
+ {'score': None,
+ 'label': 'wall',
+ 'mask': },
+ {'score': None,
+ 'label': 'pole',
+ 'mask': },
+ {'score': None,
+ 'label': 'traffic sign',
+ 'mask': },
+ {'score': None,
+ 'label': 'vegetation',
+ 'mask': },
+ {'score': None,
+ 'label': 'terrain',
+ 'mask': },
+ {'score': None,
+ 'label': 'sky',
+ 'mask': },
+ {'score': None,
+ 'label': 'car',
+ 'mask': }]
+```
+
+Taking a look at the mask for the car class, we can see every car is classified with the same mask.
+
+```python
+results[-1]["mask"]
+```
+
+
+
},
+ {'score': 0.999945,
+ 'label': 'car',
+ 'mask': },
+ {'score': 0.999652,
+ 'label': 'car',
+ 'mask': },
+ {'score': 0.903529,
+ 'label': 'person',
+ 'mask': }]
+```
+Checking out one of the car masks below.
+
+```python
+results[2]["mask"]
+```
+
+
+
},
+ {'score': 0.999958,
+ 'label': 'car',
+ 'mask': },
+ {'score': 0.99997,
+ 'label': 'vegetation',
+ 'mask': },
+ {'score': 0.999575,
+ 'label': 'pole',
+ 'mask': },
+ {'score': 0.999958,
+ 'label': 'building',
+ 'mask': },
+ {'score': 0.999634,
+ 'label': 'road',
+ 'mask': },
+ {'score': 0.996092,
+ 'label': 'sidewalk',
+ 'mask': },
+ {'score': 0.999221,
+ 'label': 'car',
+ 'mask': },
+ {'score': 0.99987,
+ 'label': 'sky',
+ 'mask': }]
+```
+
+Let's have a side by side comparison for all types of segmentation.
+
+
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/image-segmentation)
+
+
+
+
+### Load SceneParse150 dataset
+
+Start by loading a smaller subset of the SceneParse150 dataset from the 🤗 Datasets library. This'll give you a chance to experiment and make sure everything works before spending more time training on the full dataset.
+
+```py
+>>> from datasets import load_dataset
+
+>>> ds = load_dataset("scene_parse_150", split="train[:50]")
+```
+
+Split the dataset's `train` split into a train and test set with the [`~datasets.Dataset.train_test_split`] method:
+
+```py
+>>> ds = ds.train_test_split(test_size=0.2)
+>>> train_ds = ds["train"]
+>>> test_ds = ds["test"]
+```
+
+Then take a look at an example:
+
+```py
+>>> train_ds[0]
+{'image': ,
+ 'annotation': ,
+ 'scene_category': 368}
+
+# view the image
+>>> train_ds[0]["image"]
+```
+
+- `image`: a PIL image of the scene.
+- `annotation`: a PIL image of the segmentation map, which is also the model's target.
+- `scene_category`: a category id that describes the image scene like "kitchen" or "office". In this guide, you'll only need `image` and `annotation`, both of which are PIL images.
+
+You'll also want to create a dictionary that maps a label id to a label class which will be useful when you set up the model later. Download the mappings from the Hub and create the `id2label` and `label2id` dictionaries:
+
+```py
+>>> import json
+>>> from pathlib import Path
+>>> from huggingface_hub import hf_hub_download
+
+>>> repo_id = "huggingface/label-files"
+>>> filename = "ade20k-id2label.json"
+>>> id2label = json.loads(Path(hf_hub_download(repo_id, filename, repo_type="dataset")).read_text())
+>>> id2label = {int(k): v for k, v in id2label.items()}
+>>> label2id = {v: k for k, v in id2label.items()}
+>>> num_labels = len(id2label)
+```
+
+#### Custom dataset
+
+You could also create and use your own dataset if you prefer to train with the [run_semantic_segmentation.py](https://github.com/huggingface/transformers/blob/main/examples/pytorch/semantic-segmentation/run_semantic_segmentation.py) script instead of a notebook instance. The script requires:
+
+1. a [`~datasets.DatasetDict`] with two [`~datasets.Image`] columns, "image" and "label"
+
+ ```py
+ from datasets import Dataset, DatasetDict, Image
+
+ image_paths_train = ["path/to/image_1.jpg/jpg", "path/to/image_2.jpg/jpg", ..., "path/to/image_n.jpg/jpg"]
+ label_paths_train = ["path/to/annotation_1.png", "path/to/annotation_2.png", ..., "path/to/annotation_n.png"]
+
+ image_paths_validation = [...]
+ label_paths_validation = [...]
+
+ def create_dataset(image_paths, label_paths):
+ dataset = Dataset.from_dict({"image": sorted(image_paths),
+ "label": sorted(label_paths)})
+ dataset = dataset.cast_column("image", Image())
+ dataset = dataset.cast_column("label", Image())
+ return dataset
+
+ # step 1: create Dataset objects
+ train_dataset = create_dataset(image_paths_train, label_paths_train)
+ validation_dataset = create_dataset(image_paths_validation, label_paths_validation)
+
+ # step 2: create DatasetDict
+ dataset = DatasetDict({
+ "train": train_dataset,
+ "validation": validation_dataset,
+ }
+ )
+
+ # step 3: push to Hub (assumes you have ran the huggingface-cli login command in a terminal/notebook)
+ dataset.push_to_hub("your-name/dataset-repo")
+
+ # optionally, you can push to a private repo on the Hub
+ # dataset.push_to_hub("name of repo on the hub", private=True)
+ ```
+
+2. an id2label dictionary mapping the class integers to their class names
+
+ ```py
+ import json
+ # simple example
+ id2label = {0: 'cat', 1: 'dog'}
+ with open('id2label.json', 'w') as fp:
+ json.dump(id2label, fp)
+ ```
+
+As an example, take a look at this [example dataset](https://huggingface.co/datasets/nielsr/ade20k-demo) which was created with the steps shown above.
+
+### Preprocess
+
+The next step is to load a SegFormer image processor to prepare the images and annotations for the model. Some datasets, like this one, use the zero-index as the background class. However, the background class isn't actually included in the 150 classes, so you'll need to set `do_reduce_labels=True` to subtract one from all the labels. The zero-index is replaced by `255` so it's ignored by SegFormer's loss function:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> checkpoint = "nvidia/mit-b0"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint, do_reduce_labels=True)
+```
+
+
+
+
+It is common to apply some data augmentations to an image dataset to make a model more robust against overfitting. In this guide, you'll use the [`ColorJitter`](https://pytorch.org/vision/stable/generated/torchvision.transforms.ColorJitter.html) function from [torchvision](https://pytorch.org/vision/stable/index.html) to randomly change the color properties of an image, but you can also use any image library you like.
+
+```py
+>>> from torchvision.transforms import ColorJitter
+
+>>> jitter = ColorJitter(brightness=0.25, contrast=0.25, saturation=0.25, hue=0.1)
+```
+
+Now create two preprocessing functions to prepare the images and annotations for the model. These functions convert the images into `pixel_values` and annotations to `labels`. For the training set, `jitter` is applied before providing the images to the image processor. For the test set, the image processor crops and normalizes the `images`, and only crops the `labels` because no data augmentation is applied during testing.
+
+```py
+>>> def train_transforms(example_batch):
+... images = [jitter(x) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+
+
+>>> def val_transforms(example_batch):
+... images = [x for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+```
+
+To apply the `jitter` over the entire dataset, use the 🤗 Datasets [`~datasets.Dataset.set_transform`] function. The transform is applied on the fly which is faster and consumes less disk space:
+
+```py
+>>> train_ds.set_transform(train_transforms)
+>>> test_ds.set_transform(val_transforms)
+```
+
+
+
+
+
+
+It is common to apply some data augmentations to an image dataset to make a model more robust against overfitting.
+In this guide, you'll use [`tf.image`](https://www.tensorflow.org/api_docs/python/tf/image) to randomly change the color properties of an image, but you can also use any image
+library you like.
+Define two separate transformation functions:
+- training data transformations that include image augmentation
+- validation data transformations that only transpose the images, since computer vision models in 🤗 Transformers expect channels-first layout
+
+```py
+>>> import tensorflow as tf
+
+
+>>> def aug_transforms(image):
+... image = tf.keras.utils.img_to_array(image)
+... image = tf.image.random_brightness(image, 0.25)
+... image = tf.image.random_contrast(image, 0.5, 2.0)
+... image = tf.image.random_saturation(image, 0.75, 1.25)
+... image = tf.image.random_hue(image, 0.1)
+... image = tf.transpose(image, (2, 0, 1))
+... return image
+
+
+>>> def transforms(image):
+... image = tf.keras.utils.img_to_array(image)
+... image = tf.transpose(image, (2, 0, 1))
+... return image
+```
+
+Next, create two preprocessing functions to prepare batches of images and annotations for the model. These functions apply
+the image transformations and use the earlier loaded `image_processor` to convert the images into `pixel_values` and
+annotations to `labels`. `ImageProcessor` also takes care of resizing and normalizing the images.
+
+```py
+>>> def train_transforms(example_batch):
+... images = [aug_transforms(x.convert("RGB")) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+
+
+>>> def val_transforms(example_batch):
+... images = [transforms(x.convert("RGB")) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+```
+
+To apply the preprocessing transformations over the entire dataset, use the 🤗 Datasets [`~datasets.Dataset.set_transform`] function.
+The transform is applied on the fly which is faster and consumes less disk space:
+
+```py
+>>> train_ds.set_transform(train_transforms)
+>>> test_ds.set_transform(val_transforms)
+```
+
+
+
+### Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load an evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load the [mean Intersection over Union](https://huggingface.co/spaces/evaluate-metric/accuracy) (IoU) metric (see the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about how to load and compute a metric):
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("mean_iou")
+```
+
+Then create a function to [`~evaluate.EvaluationModule.compute`] the metrics. Your predictions need to be converted to
+logits first, and then reshaped to match the size of the labels before you can call [`~evaluate.EvaluationModule.compute`]:
+
+
+
+
+```py
+>>> import numpy as np
+>>> import torch
+>>> from torch import nn
+
+>>> def compute_metrics(eval_pred):
+... with torch.no_grad():
+... logits, labels = eval_pred
+... logits_tensor = torch.from_numpy(logits)
+... logits_tensor = nn.functional.interpolate(
+... logits_tensor,
+... size=labels.shape[-2:],
+... mode="bilinear",
+... align_corners=False,
+... ).argmax(dim=1)
+
+... pred_labels = logits_tensor.detach().cpu().numpy()
+... metrics = metric.compute(
+... predictions=pred_labels,
+... references=labels,
+... num_labels=num_labels,
+... ignore_index=255,
+... reduce_labels=False,
+... )
+... for key, value in metrics.items():
+... if isinstance(value, np.ndarray):
+... metrics[key] = value.tolist()
+... return metrics
+```
+
+
+
+
+
+
+
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... logits = tf.transpose(logits, perm=[0, 2, 3, 1])
+... logits_resized = tf.image.resize(
+... logits,
+... size=tf.shape(labels)[1:],
+... method="bilinear",
+... )
+
+... pred_labels = tf.argmax(logits_resized, axis=-1)
+... metrics = metric.compute(
+... predictions=pred_labels,
+... references=labels,
+... num_labels=num_labels,
+... ignore_index=-1,
+... reduce_labels=image_processor.do_reduce_labels,
+... )
+
+... per_category_accuracy = metrics.pop("per_category_accuracy").tolist()
+... per_category_iou = metrics.pop("per_category_iou").tolist()
+
+... metrics.update({f"accuracy_{id2label[i]}": v for i, v in enumerate(per_category_accuracy)})
+... metrics.update({f"iou_{id2label[i]}": v for i, v in enumerate(per_category_iou)})
+... return {"val_" + k: v for k, v in metrics.items()}
+```
+
+
+
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you setup your training.
+
+### Train
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#finetune-with-trainer)!
+
+
+
+You're ready to start training your model now! Load SegFormer with [`AutoModelForSemanticSegmentation`], and pass the model the mapping between label ids and label classes:
+
+```py
+>>> from transformers import AutoModelForSemanticSegmentation, TrainingArguments, Trainer
+
+>>> model = AutoModelForSemanticSegmentation.from_pretrained(checkpoint, id2label=id2label, label2id=label2id)
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. It is important you don't remove unused columns because this'll drop the `image` column. Without the `image` column, you can't create `pixel_values`. Set `remove_unused_columns=False` to prevent this behavior! The only other required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the IoU metric and save the training checkpoint.
+2. Pass the training arguments to [`Trainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="segformer-b0-scene-parse-150",
+... learning_rate=6e-5,
+... num_train_epochs=50,
+... per_device_train_batch_size=2,
+... per_device_eval_batch_size=2,
+... save_total_limit=3,
+... eval_strategy="steps",
+... save_strategy="steps",
+... save_steps=20,
+... eval_steps=20,
+... logging_steps=1,
+... eval_accumulation_steps=5,
+... remove_unused_columns=False,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=train_ds,
+... eval_dataset=test_ds,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+
+
+If you are unfamiliar with fine-tuning a model with Keras, check out the [basic tutorial](./training#train-a-tensorflow-model-with-keras) first!
+
+
+
+To fine-tune a model in TensorFlow, follow these steps:
+1. Define the training hyperparameters, and set up an optimizer and a learning rate schedule.
+2. Instantiate a pretrained model.
+3. Convert a 🤗 Dataset to a `tf.data.Dataset`.
+4. Compile your model.
+5. Add callbacks to calculate metrics and upload your model to 🤗 Hub
+6. Use the `fit()` method to run the training.
+
+Start by defining the hyperparameters, optimizer and learning rate schedule:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 2
+>>> num_epochs = 50
+>>> num_train_steps = len(train_ds) * num_epochs
+>>> learning_rate = 6e-5
+>>> weight_decay_rate = 0.01
+
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=learning_rate,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=weight_decay_rate,
+... num_warmup_steps=0,
+... )
+```
+
+Then, load SegFormer with [`TFAutoModelForSemanticSegmentation`] along with the label mappings, and compile it with the
+optimizer. Note that Transformers models all have a default task-relevant loss function, so you don't need to specify one unless you want to:
+
+```py
+>>> from transformers import TFAutoModelForSemanticSegmentation
+
+>>> model = TFAutoModelForSemanticSegmentation.from_pretrained(
+... checkpoint,
+... id2label=id2label,
+... label2id=label2id,
+... )
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+Convert your datasets to the `tf.data.Dataset` format using the [`~datasets.Dataset.to_tf_dataset`] and the [`DefaultDataCollator`]:
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+
+>>> tf_train_dataset = train_ds.to_tf_dataset(
+... columns=["pixel_values", "label"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+
+>>> tf_eval_dataset = test_ds.to_tf_dataset(
+... columns=["pixel_values", "label"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+```
+
+To compute the accuracy from the predictions and push your model to the 🤗 Hub, use [Keras callbacks](../main_classes/keras_callbacks).
+Pass your `compute_metrics` function to [`KerasMetricCallback`],
+and use the [`PushToHubCallback`] to upload the model:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback, PushToHubCallback
+
+>>> metric_callback = KerasMetricCallback(
+... metric_fn=compute_metrics, eval_dataset=tf_eval_dataset, batch_size=batch_size, label_cols=["labels"]
+... )
+
+>>> push_to_hub_callback = PushToHubCallback(output_dir="scene_segmentation", tokenizer=image_processor)
+
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+Finally, you are ready to train your model! Call `fit()` with your training and validation datasets, the number of epochs,
+and your callbacks to fine-tune the model:
+
+```py
+>>> model.fit(
+... tf_train_dataset,
+... validation_data=tf_eval_dataset,
+... callbacks=callbacks,
+... epochs=num_epochs,
+... )
+```
+
+Congratulations! You have fine-tuned your model and shared it on the 🤗 Hub. You can now use it for inference!
+
+
+
+### Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Reload the dataset and load an image for inference.
+
+```py
+>>> from datasets import load_dataset
+
+>>> ds = load_dataset("scene_parse_150", split="train[:50]")
+>>> ds = ds.train_test_split(test_size=0.2)
+>>> test_ds = ds["test"]
+>>> image = ds["test"][0]["image"]
+>>> image
+```
+
+
+
+
+
+
+We will now see how to infer without a pipeline. Process the image with an image processor and place the `pixel_values` on a GPU:
+
+```py
+>>> from accelerate.test_utils.testing import get_backend
+# automatically detects the underlying device type (CUDA, CPU, XPU, MPS, etc.)
+>>> device, _, _ = get_backend()
+>>> encoding = image_processor(image, return_tensors="pt")
+>>> pixel_values = encoding.pixel_values.to(device)
+```
+
+Pass your input to the model and return the `logits`:
+
+```py
+>>> outputs = model(pixel_values=pixel_values)
+>>> logits = outputs.logits.cpu()
+```
+
+Next, rescale the logits to the original image size:
+
+```py
+>>> upsampled_logits = nn.functional.interpolate(
+... logits,
+... size=image.size[::-1],
+... mode="bilinear",
+... align_corners=False,
+... )
+
+>>> pred_seg = upsampled_logits.argmax(dim=1)[0]
+```
+
+
+
+
+
+
+Load an image processor to preprocess the image and return the input as TensorFlow tensors:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("MariaK/scene_segmentation")
+>>> inputs = image_processor(image, return_tensors="tf")
+```
+
+Pass your input to the model and return the `logits`:
+
+```py
+>>> from transformers import TFAutoModelForSemanticSegmentation
+
+>>> model = TFAutoModelForSemanticSegmentation.from_pretrained("MariaK/scene_segmentation")
+>>> logits = model(**inputs).logits
+```
+
+Next, rescale the logits to the original image size and apply argmax on the class dimension:
+```py
+>>> logits = tf.transpose(logits, [0, 2, 3, 1])
+
+>>> upsampled_logits = tf.image.resize(
+... logits,
+... # We reverse the shape of `image` because `image.size` returns width and height.
+... image.size[::-1],
+... )
+
+>>> pred_seg = tf.math.argmax(upsampled_logits, axis=-1)[0]
+```
+
+
+
+
+To visualize the results, load the [dataset color palette](https://github.com/tensorflow/models/blob/3f1ca33afe3c1631b733ea7e40c294273b9e406d/research/deeplab/utils/get_dataset_colormap.py#L51) as `ade_palette()` that maps each class to their RGB values.
+
+```py
+def ade_palette():
+ return np.asarray([
+ [0, 0, 0],
+ [120, 120, 120],
+ [180, 120, 120],
+ [6, 230, 230],
+ [80, 50, 50],
+ [4, 200, 3],
+ [120, 120, 80],
+ [140, 140, 140],
+ [204, 5, 255],
+ [230, 230, 230],
+ [4, 250, 7],
+ [224, 5, 255],
+ [235, 255, 7],
+ [150, 5, 61],
+ [120, 120, 70],
+ [8, 255, 51],
+ [255, 6, 82],
+ [143, 255, 140],
+ [204, 255, 4],
+ [255, 51, 7],
+ [204, 70, 3],
+ [0, 102, 200],
+ [61, 230, 250],
+ [255, 6, 51],
+ [11, 102, 255],
+ [255, 7, 71],
+ [255, 9, 224],
+ [9, 7, 230],
+ [220, 220, 220],
+ [255, 9, 92],
+ [112, 9, 255],
+ [8, 255, 214],
+ [7, 255, 224],
+ [255, 184, 6],
+ [10, 255, 71],
+ [255, 41, 10],
+ [7, 255, 255],
+ [224, 255, 8],
+ [102, 8, 255],
+ [255, 61, 6],
+ [255, 194, 7],
+ [255, 122, 8],
+ [0, 255, 20],
+ [255, 8, 41],
+ [255, 5, 153],
+ [6, 51, 255],
+ [235, 12, 255],
+ [160, 150, 20],
+ [0, 163, 255],
+ [140, 140, 140],
+ [250, 10, 15],
+ [20, 255, 0],
+ [31, 255, 0],
+ [255, 31, 0],
+ [255, 224, 0],
+ [153, 255, 0],
+ [0, 0, 255],
+ [255, 71, 0],
+ [0, 235, 255],
+ [0, 173, 255],
+ [31, 0, 255],
+ [11, 200, 200],
+ [255, 82, 0],
+ [0, 255, 245],
+ [0, 61, 255],
+ [0, 255, 112],
+ [0, 255, 133],
+ [255, 0, 0],
+ [255, 163, 0],
+ [255, 102, 0],
+ [194, 255, 0],
+ [0, 143, 255],
+ [51, 255, 0],
+ [0, 82, 255],
+ [0, 255, 41],
+ [0, 255, 173],
+ [10, 0, 255],
+ [173, 255, 0],
+ [0, 255, 153],
+ [255, 92, 0],
+ [255, 0, 255],
+ [255, 0, 245],
+ [255, 0, 102],
+ [255, 173, 0],
+ [255, 0, 20],
+ [255, 184, 184],
+ [0, 31, 255],
+ [0, 255, 61],
+ [0, 71, 255],
+ [255, 0, 204],
+ [0, 255, 194],
+ [0, 255, 82],
+ [0, 10, 255],
+ [0, 112, 255],
+ [51, 0, 255],
+ [0, 194, 255],
+ [0, 122, 255],
+ [0, 255, 163],
+ [255, 153, 0],
+ [0, 255, 10],
+ [255, 112, 0],
+ [143, 255, 0],
+ [82, 0, 255],
+ [163, 255, 0],
+ [255, 235, 0],
+ [8, 184, 170],
+ [133, 0, 255],
+ [0, 255, 92],
+ [184, 0, 255],
+ [255, 0, 31],
+ [0, 184, 255],
+ [0, 214, 255],
+ [255, 0, 112],
+ [92, 255, 0],
+ [0, 224, 255],
+ [112, 224, 255],
+ [70, 184, 160],
+ [163, 0, 255],
+ [153, 0, 255],
+ [71, 255, 0],
+ [255, 0, 163],
+ [255, 204, 0],
+ [255, 0, 143],
+ [0, 255, 235],
+ [133, 255, 0],
+ [255, 0, 235],
+ [245, 0, 255],
+ [255, 0, 122],
+ [255, 245, 0],
+ [10, 190, 212],
+ [214, 255, 0],
+ [0, 204, 255],
+ [20, 0, 255],
+ [255, 255, 0],
+ [0, 153, 255],
+ [0, 41, 255],
+ [0, 255, 204],
+ [41, 0, 255],
+ [41, 255, 0],
+ [173, 0, 255],
+ [0, 245, 255],
+ [71, 0, 255],
+ [122, 0, 255],
+ [0, 255, 184],
+ [0, 92, 255],
+ [184, 255, 0],
+ [0, 133, 255],
+ [255, 214, 0],
+ [25, 194, 194],
+ [102, 255, 0],
+ [92, 0, 255],
+ ])
+```
+
+Then you can combine and plot your image and the predicted segmentation map:
+
+```py
+>>> import matplotlib.pyplot as plt
+>>> import numpy as np
+
+>>> color_seg = np.zeros((pred_seg.shape[0], pred_seg.shape[1], 3), dtype=np.uint8)
+>>> palette = np.array(ade_palette())
+>>> for label, color in enumerate(palette):
+... color_seg[pred_seg == label, :] = color
+>>> color_seg = color_seg[..., ::-1] # convert to BGR
+
+>>> img = np.array(image) * 0.5 + color_seg * 0.5 # plot the image with the segmentation map
+>>> img = img.astype(np.uint8)
+
+>>> plt.figure(figsize=(15, 10))
+>>> plt.imshow(img)
+>>> plt.show()
+```
+
+
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/text-classification).
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate accelerate
+```
+
+We encourage you to login to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load IMDb dataset
+
+Start by loading the IMDb dataset from the 🤗 Datasets library:
+
+```py
+>>> from datasets import load_dataset
+
+>>> imdb = load_dataset("imdb")
+```
+
+Then take a look at an example:
+
+```py
+>>> imdb["test"][0]
+{
+ "label": 0,
+ "text": "I love sci-fi and am willing to put up with a lot. Sci-fi movies/TV are usually underfunded, under-appreciated and misunderstood. I tried to like this, I really did, but it is to good TV sci-fi as Babylon 5 is to Star Trek (the original). Silly prosthetics, cheap cardboard sets, stilted dialogues, CG that doesn't match the background, and painfully one-dimensional characters cannot be overcome with a 'sci-fi' setting. (I'm sure there are those of you out there who think Babylon 5 is good sci-fi TV. It's not. It's clichéd and uninspiring.) While US viewers might like emotion and character development, sci-fi is a genre that does not take itself seriously (cf. Star Trek). It may treat important issues, yet not as a serious philosophy. It's really difficult to care about the characters here as they are not simply foolish, just missing a spark of life. Their actions and reactions are wooden and predictable, often painful to watch. The makers of Earth KNOW it's rubbish as they have to always say \"Gene Roddenberry's Earth...\" otherwise people would not continue watching. Roddenberry's ashes must be turning in their orbit as this dull, cheap, poorly edited (watching it without advert breaks really brings this home) trudging Trabant of a show lumbers into space. Spoiler. So, kill off a main character. And then bring him back as another actor. Jeeez! Dallas all over again.",
+}
+```
+
+There are two fields in this dataset:
+
+- `text`: the movie review text.
+- `label`: a value that is either `0` for a negative review or `1` for a positive review.
+
+## Preprocess
+
+The next step is to load a DistilBERT tokenizer to preprocess the `text` field:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Create a preprocessing function to tokenize `text` and truncate sequences to be no longer than DistilBERT's maximum input length:
+
+```py
+>>> def preprocess_function(examples):
+... return tokenizer(examples["text"], truncation=True)
+```
+
+To apply the preprocessing function over the entire dataset, use 🤗 Datasets [`~datasets.Dataset.map`] function. You can speed up `map` by setting `batched=True` to process multiple elements of the dataset at once:
+
+```py
+tokenized_imdb = imdb.map(preprocess_function, batched=True)
+```
+
+Now create a batch of examples using [`DataCollatorWithPadding`]. It's more efficient to *dynamically pad* the sentences to the longest length in a batch during collation, instead of padding the whole dataset to the maximum length.
+
+
+
+```py
+>>> from transformers import DataCollatorWithPadding
+
+>>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+```
+
+
+```py
+>>> from transformers import DataCollatorWithPadding
+
+>>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer, return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load a evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load the [accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) metric (see the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about how to load and compute a metric):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+Then create a function that passes your predictions and labels to [`~evaluate.EvaluationModule.compute`] to calculate the accuracy:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... predictions = np.argmax(predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=labels)
+```
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you setup your training.
+
+## Train
+
+Before you start training your model, create a map of the expected ids to their labels with `id2label` and `label2id`:
+
+```py
+>>> id2label = {0: "NEGATIVE", 1: "POSITIVE"}
+>>> label2id = {"NEGATIVE": 0, "POSITIVE": 1}
+```
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load DistilBERT with [`AutoModelForSequenceClassification`] along with the number of expected labels, and the label mappings:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=2, id2label=id2label, label2id=label2id
+... )
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the accuracy and save the training checkpoint.
+2. Pass the training arguments to [`Trainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_model",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=2,
+... weight_decay=0.01,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... load_best_model_at_end=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_imdb["train"],
+... eval_dataset=tokenized_imdb["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+
+
+[`Trainer`] applies dynamic padding by default when you pass `tokenizer` to it. In this case, you don't need to specify a data collator explicitly.
+
+
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+If you aren't familiar with finetuning a model with Keras, take a look at the basic tutorial [here](../training#train-a-tensorflow-model-with-keras)!
+
+
+To finetune a model in TensorFlow, start by setting up an optimizer function, learning rate schedule, and some training hyperparameters:
+
+```py
+>>> from transformers import create_optimizer
+>>> import tensorflow as tf
+
+>>> batch_size = 16
+>>> num_epochs = 5
+>>> batches_per_epoch = len(tokenized_imdb["train"]) // batch_size
+>>> total_train_steps = int(batches_per_epoch * num_epochs)
+>>> optimizer, schedule = create_optimizer(init_lr=2e-5, num_warmup_steps=0, num_train_steps=total_train_steps)
+```
+
+Then you can load DistilBERT with [`TFAutoModelForSequenceClassification`] along with the number of expected labels, and the label mappings:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=2, id2label=id2label, label2id=label2id
+... )
+```
+
+Convert your datasets to the `tf.data.Dataset` format with [`~transformers.TFPreTrainedModel.prepare_tf_dataset`]:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_imdb["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_imdb["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+Configure the model for training with [`compile`](https://keras.io/api/models/model_training_apis/#compile-method). Note that Transformers models all have a default task-relevant loss function, so you don't need to specify one unless you want to:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+The last two things to setup before you start training is to compute the accuracy from the predictions, and provide a way to push your model to the Hub. Both are done by using [Keras callbacks](../main_classes/keras_callbacks).
+
+Pass your `compute_metrics` function to [`~transformers.KerasMetricCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+Specify where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_model",
+... tokenizer=tokenizer,
+... )
+```
+
+Then bundle your callbacks together:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+Finally, you're ready to start training your model! Call [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) with your training and validation datasets, the number of epochs, and your callbacks to finetune the model:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=callbacks)
+```
+
+Once training is completed, your model is automatically uploaded to the Hub so everyone can use it!
+
+
+
+
+
+For a more in-depth example of how to finetune a model for text classification, take a look at the corresponding
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb)
+or [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification-tf.ipynb).
+
+
+
+## Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Grab some text you'd like to run inference on:
+
+```py
+>>> text = "This was a masterpiece. Not completely faithful to the books, but enthralling from beginning to end. Might be my favorite of the three."
+```
+
+The simplest way to try out your finetuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for sentiment analysis with your model, and pass your text to it:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("sentiment-analysis", model="stevhliu/my_awesome_model")
+>>> classifier(text)
+[{'label': 'POSITIVE', 'score': 0.9994940757751465}]
+```
+
+You can also manually replicate the results of the `pipeline` if you'd like:
+
+
+
+Tokenize the text and return PyTorch tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+```
+
+Pass your inputs to the model and return the `logits`:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("stevhliu/my_awesome_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+Get the class with the highest probability, and use the model's `id2label` mapping to convert it to a text label:
+
+```py
+>>> predicted_class_id = logits.argmax().item()
+>>> model.config.id2label[predicted_class_id]
+'POSITIVE'
+```
+
+
+Tokenize the text and return TensorFlow tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+```
+
+Pass your inputs to the model and return the `logits`:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("stevhliu/my_awesome_model")
+>>> logits = model(**inputs).logits
+```
+
+Get the class with the highest probability, and use the model's `id2label` mapping to convert it to a text label:
+
+```py
+>>> predicted_class_id = int(tf.math.argmax(logits, axis=-1)[0])
+>>> model.config.id2label[predicted_class_id]
+'POSITIVE'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/summarization.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/summarization.md
new file mode 100644
index 0000000000000000000000000000000000000000..e16dd17dfe1fc8186cd0f121f5f794d0f7f7c16e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/summarization.md
@@ -0,0 +1,400 @@
+
+
+# Summarization
+
+[[open-in-colab]]
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/summarization)
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate rouge_score
+```
+
+We encourage you to login to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load BillSum dataset
+
+Start by loading the smaller California state bill subset of the BillSum dataset from the 🤗 Datasets library:
+
+```py
+>>> from datasets import load_dataset
+
+>>> billsum = load_dataset("billsum", split="ca_test")
+```
+
+Split the dataset into a train and test set with the [`~datasets.Dataset.train_test_split`] method:
+
+```py
+>>> billsum = billsum.train_test_split(test_size=0.2)
+```
+
+Then take a look at an example:
+
+```py
+>>> billsum["train"][0]
+{'summary': 'Existing law authorizes state agencies to enter into contracts for the acquisition of goods or services upon approval by the Department of General Services. Existing law sets forth various requirements and prohibitions for those contracts, including, but not limited to, a prohibition on entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between spouses and domestic partners or same-sex and different-sex couples in the provision of benefits. Existing law provides that a contract entered into in violation of those requirements and prohibitions is void and authorizes the state or any person acting on behalf of the state to bring a civil action seeking a determination that a contract is in violation and therefore void. Under existing law, a willful violation of those requirements and prohibitions is a misdemeanor.\nThis bill would also prohibit a state agency from entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between employees on the basis of gender identity in the provision of benefits, as specified. By expanding the scope of a crime, this bill would impose a state-mandated local program.\nThe California Constitution requires the state to reimburse local agencies and school districts for certain costs mandated by the state. Statutory provisions establish procedures for making that reimbursement.\nThis bill would provide that no reimbursement is required by this act for a specified reason.',
+ 'text': 'The people of the State of California do enact as follows:\n\n\nSECTION 1.\nSection 10295.35 is added to the Public Contract Code, to read:\n10295.35.\n(a) (1) Notwithstanding any other law, a state agency shall not enter into any contract for the acquisition of goods or services in the amount of one hundred thousand dollars ($100,000) or more with a contractor that, in the provision of benefits, discriminates between employees on the basis of an employee’s or dependent’s actual or perceived gender identity, including, but not limited to, the employee’s or dependent’s identification as transgender.\n(2) For purposes of this section, “contract” includes contracts with a cumulative amount of one hundred thousand dollars ($100,000) or more per contractor in each fiscal year.\n(3) For purposes of this section, an employee health plan is discriminatory if the plan is not consistent with Section 1365.5 of the Health and Safety Code and Section 10140 of the Insurance Code.\n(4) The requirements of this section shall apply only to those portions of a contractor’s operations that occur under any of the following conditions:\n(A) Within the state.\n(B) On real property outside the state if the property is owned by the state or if the state has a right to occupy the property, and if the contractor’s presence at that location is connected to a contract with the state.\n(C) Elsewhere in the United States where work related to a state contract is being performed.\n(b) Contractors shall treat as confidential, to the maximum extent allowed by law or by the requirement of the contractor’s insurance provider, any request by an employee or applicant for employment benefits or any documentation of eligibility for benefits submitted by an employee or applicant for employment.\n(c) After taking all reasonable measures to find a contractor that complies with this section, as determined by the state agency, the requirements of this section may be waived under any of the following circumstances:\n(1) There is only one prospective contractor willing to enter into a specific contract with the state agency.\n(2) The contract is necessary to respond to an emergency, as determined by the state agency, that endangers the public health, welfare, or safety, or the contract is necessary for the provision of essential services, and no entity that complies with the requirements of this section capable of responding to the emergency is immediately available.\n(3) The requirements of this section violate, or are inconsistent with, the terms or conditions of a grant, subvention, or agreement, if the agency has made a good faith attempt to change the terms or conditions of any grant, subvention, or agreement to authorize application of this section.\n(4) The contractor is providing wholesale or bulk water, power, or natural gas, the conveyance or transmission of the same, or ancillary services, as required for ensuring reliable services in accordance with good utility practice, if the purchase of the same cannot practically be accomplished through the standard competitive bidding procedures and the contractor is not providing direct retail services to end users.\n(d) (1) A contractor shall not be deemed to discriminate in the provision of benefits if the contractor, in providing the benefits, pays the actual costs incurred in obtaining the benefit.\n(2) If a contractor is unable to provide a certain benefit, despite taking reasonable measures to do so, the contractor shall not be deemed to discriminate in the provision of benefits.\n(e) (1) Every contract subject to this chapter shall contain a statement by which the contractor certifies that the contractor is in compliance with this section.\n(2) The department or other contracting agency shall enforce this section pursuant to its existing enforcement powers.\n(3) (A) If a contractor falsely certifies that it is in compliance with this section, the contract with that contractor shall be subject to Article 9 (commencing with Section 10420), unless, within a time period specified by the department or other contracting agency, the contractor provides to the department or agency proof that it has complied, or is in the process of complying, with this section.\n(B) The application of the remedies or penalties contained in Article 9 (commencing with Section 10420) to a contract subject to this chapter shall not preclude the application of any existing remedies otherwise available to the department or other contracting agency under its existing enforcement powers.\n(f) Nothing in this section is intended to regulate the contracting practices of any local jurisdiction.\n(g) This section shall be construed so as not to conflict with applicable federal laws, rules, or regulations. In the event that a court or agency of competent jurisdiction holds that federal law, rule, or regulation invalidates any clause, sentence, paragraph, or section of this code or the application thereof to any person or circumstances, it is the intent of the state that the court or agency sever that clause, sentence, paragraph, or section so that the remainder of this section shall remain in effect.\nSEC. 2.\nSection 10295.35 of the Public Contract Code shall not be construed to create any new enforcement authority or responsibility in the Department of General Services or any other contracting agency.\nSEC. 3.\nNo reimbursement is required by this act pursuant to Section 6 of Article XIII\u2009B of the California Constitution because the only costs that may be incurred by a local agency or school district will be incurred because this act creates a new crime or infraction, eliminates a crime or infraction, or changes the penalty for a crime or infraction, within the meaning of Section 17556 of the Government Code, or changes the definition of a crime within the meaning of Section 6 of Article XIII\u2009B of the California Constitution.',
+ 'title': 'An act to add Section 10295.35 to the Public Contract Code, relating to public contracts.'}
+```
+
+There are two fields that you'll want to use:
+
+- `text`: the text of the bill which'll be the input to the model.
+- `summary`: a condensed version of `text` which'll be the model target.
+
+## Preprocess
+
+The next step is to load a T5 tokenizer to process `text` and `summary`:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> checkpoint = "google-t5/t5-small"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+```
+
+The preprocessing function you want to create needs to:
+
+1. Prefix the input with a prompt so T5 knows this is a summarization task. Some models capable of multiple NLP tasks require prompting for specific tasks.
+2. Use the keyword `text_target` argument when tokenizing labels.
+3. Truncate sequences to be no longer than the maximum length set by the `max_length` parameter.
+
+```py
+>>> prefix = "summarize: "
+
+
+>>> def preprocess_function(examples):
+... inputs = [prefix + doc for doc in examples["text"]]
+... model_inputs = tokenizer(inputs, max_length=1024, truncation=True)
+
+... labels = tokenizer(text_target=examples["summary"], max_length=128, truncation=True)
+
+... model_inputs["labels"] = labels["input_ids"]
+... return model_inputs
+```
+
+To apply the preprocessing function over the entire dataset, use 🤗 Datasets [`~datasets.Dataset.map`] method. You can speed up the `map` function by setting `batched=True` to process multiple elements of the dataset at once:
+
+```py
+>>> tokenized_billsum = billsum.map(preprocess_function, batched=True)
+```
+
+Now create a batch of examples using [`DataCollatorForSeq2Seq`]. It's more efficient to *dynamically pad* the sentences to the longest length in a batch during collation, instead of padding the whole dataset to the maximum length.
+
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint)
+```
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint, return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load a evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load the [ROUGE](https://huggingface.co/spaces/evaluate-metric/rouge) metric (see the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about how to load and compute a metric):
+
+```py
+>>> import evaluate
+
+>>> rouge = evaluate.load("rouge")
+```
+
+Then create a function that passes your predictions and labels to [`~evaluate.EvaluationModule.compute`] to calculate the ROUGE metric:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... decoded_preds = tokenizer.batch_decode(predictions, skip_special_tokens=True)
+... labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+... decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+... result = rouge.compute(predictions=decoded_preds, references=decoded_labels, use_stemmer=True)
+
+... prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in predictions]
+... result["gen_len"] = np.mean(prediction_lens)
+
+... return {k: round(v, 4) for k, v in result.items()}
+```
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you setup your training.
+
+## Train
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load T5 with [`AutoModelForSeq2SeqLM`]:
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM, Seq2SeqTrainingArguments, Seq2SeqTrainer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`Seq2SeqTrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the ROUGE metric and save the training checkpoint.
+2. Pass the training arguments to [`Seq2SeqTrainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = Seq2SeqTrainingArguments(
+... output_dir="my_awesome_billsum_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... weight_decay=0.01,
+... save_total_limit=3,
+... num_train_epochs=4,
+... predict_with_generate=True,
+... fp16=True, #change to bf16=True for XPU
+... push_to_hub=True,
+... )
+
+>>> trainer = Seq2SeqTrainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_billsum["train"],
+... eval_dataset=tokenized_billsum["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+If you aren't familiar with finetuning a model with Keras, take a look at the basic tutorial [here](../training#train-a-tensorflow-model-with-keras)!
+
+
+To finetune a model in TensorFlow, start by setting up an optimizer function, learning rate schedule, and some training hyperparameters:
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+Then you can load T5 with [`TFAutoModelForSeq2SeqLM`]:
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+Convert your datasets to the `tf.data.Dataset` format with [`~transformers.TFPreTrainedModel.prepare_tf_dataset`]:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_billsum["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... tokenized_billsum["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+Configure the model for training with [`compile`](https://keras.io/api/models/model_training_apis/#compile-method). Note that Transformers models all have a default task-relevant loss function, so you don't need to specify one unless you want to:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+The last two things to setup before you start training is to compute the ROUGE score from the predictions, and provide a way to push your model to the Hub. Both are done by using [Keras callbacks](../main_classes/keras_callbacks).
+
+Pass your `compute_metrics` function to [`~transformers.KerasMetricCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_test_set)
+```
+
+Specify where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_billsum_model",
+... tokenizer=tokenizer,
+... )
+```
+
+Then bundle your callbacks together:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+Finally, you're ready to start training your model! Call [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) with your training and validation datasets, the number of epochs, and your callbacks to finetune the model:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=callbacks)
+```
+
+Once training is completed, your model is automatically uploaded to the Hub so everyone can use it!
+
+
+
+
+
+For a more in-depth example of how to finetune a model for summarization, take a look at the corresponding
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization.ipynb)
+or [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization-tf.ipynb).
+
+
+
+## Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Come up with some text you'd like to summarize. For T5, you need to prefix your input depending on the task you're working on. For summarization you should prefix your input as shown below:
+
+```py
+>>> text = "summarize: The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country. It'll lower the deficit and ask the ultra-wealthy and corporations to pay their fair share. And no one making under $400,000 per year will pay a penny more in taxes."
+```
+
+The simplest way to try out your finetuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for summarization with your model, and pass your text to it:
+
+```py
+>>> from transformers import pipeline
+
+>>> summarizer = pipeline("summarization", model="username/my_awesome_billsum_model")
+>>> summarizer(text)
+[{"summary_text": "The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country."}]
+```
+
+You can also manually replicate the results of the `pipeline` if you'd like:
+
+
+
+
+Tokenize the text and return the `input_ids` as PyTorch tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_billsum_model")
+>>> inputs = tokenizer(text, return_tensors="pt").input_ids
+```
+
+Use the [`~generation.GenerationMixin.generate`] method to create the summarization. For more details about the different text generation strategies and parameters for controlling generation, check out the [Text Generation](../main_classes/text_generation) API.
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("username/my_awesome_billsum_model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
+```
+
+Decode the generated token ids back into text:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
+```
+
+
+Tokenize the text and return the `input_ids` as TensorFlow tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_billsum_model")
+>>> inputs = tokenizer(text, return_tensors="tf").input_ids
+```
+
+Use the [`~transformers.generation_tf_utils.TFGenerationMixin.generate`] method to create the summarization. For more details about the different text generation strategies and parameters for controlling generation, check out the [Text Generation](../main_classes/text_generation) API.
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained("username/my_awesome_billsum_model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
+```
+
+Decode the generated token ids back into text:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/text-to-speech.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/text-to-speech.md
new file mode 100644
index 0000000000000000000000000000000000000000..e25da4e19efeaac3666194224fcc7423220ad89f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/text-to-speech.md
@@ -0,0 +1,637 @@
+
+
+# Text to speech
+
+[[open-in-colab]]
+
+Text-to-speech (TTS) is the task of creating natural-sounding speech from text, where the speech can be generated in multiple
+languages and for multiple speakers. Several text-to-speech models are currently available in 🤗 Transformers, such as
+[Bark](../model_doc/bark), [MMS](../model_doc/mms), [VITS](../model_doc/vits) and [SpeechT5](../model_doc/speecht5).
+
+You can easily generate audio using the `"text-to-audio"` pipeline (or its alias - `"text-to-speech"`). Some models, like Bark,
+can also be conditioned to generate non-verbal communications such as laughing, sighing and crying, or even add music.
+Here's an example of how you would use the `"text-to-speech"` pipeline with Bark:
+
+```py
+>>> from transformers import pipeline
+
+>>> pipe = pipeline("text-to-speech", model="suno/bark-small")
+>>> text = "[clears throat] This is a test ... and I just took a long pause."
+>>> output = pipe(text)
+```
+
+Here's a code snippet you can use to listen to the resulting audio in a notebook:
+
+```python
+>>> from IPython.display import Audio
+>>> Audio(output["audio"], rate=output["sampling_rate"])
+```
+
+For more examples on what Bark and other pretrained TTS models can do, refer to our
+[Audio course](https://huggingface.co/learn/audio-course/chapter6/pre-trained_models).
+
+If you are looking to fine-tune a TTS model, the only text-to-speech models currently available in 🤗 Transformers
+are [SpeechT5](model_doc/speecht5) and [FastSpeech2Conformer](model_doc/fastspeech2_conformer), though more will be added in the future. SpeechT5 is pre-trained on a combination of speech-to-text and text-to-speech data, allowing it to learn a unified space of hidden representations shared by both text and speech. This means that the same pre-trained model can be fine-tuned for different tasks. Furthermore, SpeechT5 supports multiple speakers through x-vector speaker embeddings.
+
+The remainder of this guide illustrates how to:
+
+1. Fine-tune [SpeechT5](../model_doc/speecht5) that was originally trained on English speech on the Dutch (`nl`) language subset of the [VoxPopuli](https://huggingface.co/datasets/facebook/voxpopuli) dataset.
+2. Use your refined model for inference in one of two ways: using a pipeline or directly.
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install datasets soundfile speechbrain accelerate
+```
+
+Install 🤗Transformers from source as not all the SpeechT5 features have been merged into an official release yet:
+
+```bash
+pip install git+https://github.com/huggingface/transformers.git
+```
+
+
+
+To follow this guide you will need a GPU. If you're working in a notebook, run the following line to check if a GPU is available:
+
+```bash
+!nvidia-smi
+```
+
+or alternatively for AMD GPUs:
+
+```bash
+!rocm-smi
+```
+
+
+
+We encourage you to log in to your Hugging Face account to upload and share your model with the community. When prompted, enter your token to log in:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load the dataset
+
+[VoxPopuli](https://huggingface.co/datasets/facebook/voxpopuli) is a large-scale multilingual speech corpus consisting of
+data sourced from 2009-2020 European Parliament event recordings. It contains labelled audio-transcription data for 15
+European languages. In this guide, we are using the Dutch language subset, feel free to pick another subset.
+
+Note that VoxPopuli or any other automated speech recognition (ASR) dataset may not be the most suitable
+option for training TTS models. The features that make it beneficial for ASR, such as excessive background noise, are
+typically undesirable in TTS. However, finding top-quality, multilingual, and multi-speaker TTS datasets can be quite
+challenging.
+
+Let's load the data:
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("facebook/voxpopuli", "nl", split="train")
+>>> len(dataset)
+20968
+```
+
+20968 examples should be sufficient for fine-tuning. SpeechT5 expects audio data to have a sampling rate of 16 kHz, so
+make sure the examples in the dataset meet this requirement:
+
+```py
+dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+```
+
+## Preprocess the data
+
+Let's begin by defining the model checkpoint to use and loading the appropriate processor:
+
+```py
+>>> from transformers import SpeechT5Processor
+
+>>> checkpoint = "microsoft/speecht5_tts"
+>>> processor = SpeechT5Processor.from_pretrained(checkpoint)
+```
+
+### Text cleanup for SpeechT5 tokenization
+
+Start by cleaning up the text data. You'll need the tokenizer part of the processor to process the text:
+
+```py
+>>> tokenizer = processor.tokenizer
+```
+
+The dataset examples contain `raw_text` and `normalized_text` features. When deciding which feature to use as the text input,
+consider that the SpeechT5 tokenizer doesn't have any tokens for numbers. In `normalized_text` the numbers are written
+out as text. Thus, it is a better fit, and we recommend using `normalized_text` as input text.
+
+Because SpeechT5 was trained on the English language, it may not recognize certain characters in the Dutch dataset. If
+left as is, these characters will be converted to `` tokens. However, in Dutch, certain characters like `à` are
+used to stress syllables. In order to preserve the meaning of the text, we can replace this character with a regular `a`.
+
+To identify unsupported tokens, extract all unique characters in the dataset using the `SpeechT5Tokenizer` which
+works with characters as tokens. To do this, write the `extract_all_chars` mapping function that concatenates
+the transcriptions from all examples into one string and converts it to a set of characters.
+Make sure to set `batched=True` and `batch_size=-1` in `dataset.map()` so that all transcriptions are available at once for
+the mapping function.
+
+```py
+>>> def extract_all_chars(batch):
+... all_text = " ".join(batch["normalized_text"])
+... vocab = list(set(all_text))
+... return {"vocab": [vocab], "all_text": [all_text]}
+
+
+>>> vocabs = dataset.map(
+... extract_all_chars,
+... batched=True,
+... batch_size=-1,
+... keep_in_memory=True,
+... remove_columns=dataset.column_names,
+... )
+
+>>> dataset_vocab = set(vocabs["vocab"][0])
+>>> tokenizer_vocab = {k for k, _ in tokenizer.get_vocab().items()}
+```
+
+Now you have two sets of characters: one with the vocabulary from the dataset and one with the vocabulary from the tokenizer.
+To identify any unsupported characters in the dataset, you can take the difference between these two sets. The resulting
+set will contain the characters that are in the dataset but not in the tokenizer.
+
+```py
+>>> dataset_vocab - tokenizer_vocab
+{' ', 'à', 'ç', 'è', 'ë', 'í', 'ï', 'ö', 'ü'}
+```
+
+To handle the unsupported characters identified in the previous step, define a function that maps these characters to
+valid tokens. Note that spaces are already replaced by `▁` in the tokenizer and don't need to be handled separately.
+
+```py
+>>> replacements = [
+... ("à", "a"),
+... ("ç", "c"),
+... ("è", "e"),
+... ("ë", "e"),
+... ("í", "i"),
+... ("ï", "i"),
+... ("ö", "o"),
+... ("ü", "u"),
+... ]
+
+
+>>> def cleanup_text(inputs):
+... for src, dst in replacements:
+... inputs["normalized_text"] = inputs["normalized_text"].replace(src, dst)
+... return inputs
+
+
+>>> dataset = dataset.map(cleanup_text)
+```
+
+Now that you have dealt with special characters in the text, it's time to shift focus to the audio data.
+
+### Speakers
+
+The VoxPopuli dataset includes speech from multiple speakers, but how many speakers are represented in the dataset? To
+determine this, we can count the number of unique speakers and the number of examples each speaker contributes to the dataset.
+With a total of 20,968 examples in the dataset, this information will give us a better understanding of the distribution of
+speakers and examples in the data.
+
+```py
+>>> from collections import defaultdict
+
+>>> speaker_counts = defaultdict(int)
+
+>>> for speaker_id in dataset["speaker_id"]:
+... speaker_counts[speaker_id] += 1
+```
+
+By plotting a histogram you can get a sense of how much data there is for each speaker.
+
+```py
+>>> import matplotlib.pyplot as plt
+
+>>> plt.figure()
+>>> plt.hist(speaker_counts.values(), bins=20)
+>>> plt.ylabel("Speakers")
+>>> plt.xlabel("Examples")
+>>> plt.show()
+```
+
+
+
+
+
+
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/token-classification).
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate seqeval
+```
+
+We encourage you to login to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load WNUT 17 dataset
+
+Start by loading the WNUT 17 dataset from the 🤗 Datasets library:
+
+```py
+>>> from datasets import load_dataset
+
+>>> wnut = load_dataset("wnut_17")
+```
+
+Then take a look at an example:
+
+```py
+>>> wnut["train"][0]
+{'id': '0',
+ 'ner_tags': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 7, 8, 8, 0, 7, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'tokens': ['@paulwalk', 'It', "'s", 'the', 'view', 'from', 'where', 'I', "'m", 'living', 'for', 'two', 'weeks', '.', 'Empire', 'State', 'Building', '=', 'ESB', '.', 'Pretty', 'bad', 'storm', 'here', 'last', 'evening', '.']
+}
+```
+
+Each number in `ner_tags` represents an entity. Convert the numbers to their label names to find out what the entities are:
+
+```py
+>>> label_list = wnut["train"].features[f"ner_tags"].feature.names
+>>> label_list
+[
+ "O",
+ "B-corporation",
+ "I-corporation",
+ "B-creative-work",
+ "I-creative-work",
+ "B-group",
+ "I-group",
+ "B-location",
+ "I-location",
+ "B-person",
+ "I-person",
+ "B-product",
+ "I-product",
+]
+```
+
+The letter that prefixes each `ner_tag` indicates the token position of the entity:
+
+- `B-` indicates the beginning of an entity.
+- `I-` indicates a token is contained inside the same entity (for example, the `State` token is a part of an entity like
+ `Empire State Building`).
+- `0` indicates the token doesn't correspond to any entity.
+
+## Preprocess
+
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer)
+```
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer, return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load a evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load the [seqeval](https://huggingface.co/spaces/evaluate-metric/seqeval) framework (see the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about how to load and compute a metric). Seqeval actually produces several scores: precision, recall, F1, and accuracy.
+
+```py
+>>> import evaluate
+
+>>> seqeval = evaluate.load("seqeval")
+```
+
+Get the NER labels first, and then create a function that passes your true predictions and true labels to [`~evaluate.EvaluationModule.compute`] to calculate the scores:
+
+```py
+>>> import numpy as np
+
+>>> labels = [label_list[i] for i in example[f"ner_tags"]]
+
+
+>>> def compute_metrics(p):
+... predictions, labels = p
+... predictions = np.argmax(predictions, axis=2)
+
+... true_predictions = [
+... [label_list[p] for (p, l) in zip(prediction, label) if l != -100]
+... for prediction, label in zip(predictions, labels)
+... ]
+... true_labels = [
+... [label_list[l] for (p, l) in zip(prediction, label) if l != -100]
+... for prediction, label in zip(predictions, labels)
+... ]
+
+... results = seqeval.compute(predictions=true_predictions, references=true_labels)
+... return {
+... "precision": results["overall_precision"],
+... "recall": results["overall_recall"],
+... "f1": results["overall_f1"],
+... "accuracy": results["overall_accuracy"],
+... }
+```
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you setup your training.
+
+## Train
+
+Before you start training your model, create a map of the expected ids to their labels with `id2label` and `label2id`:
+
+```py
+>>> id2label = {
+... 0: "O",
+... 1: "B-corporation",
+... 2: "I-corporation",
+... 3: "B-creative-work",
+... 4: "I-creative-work",
+... 5: "B-group",
+... 6: "I-group",
+... 7: "B-location",
+... 8: "I-location",
+... 9: "B-person",
+... 10: "I-person",
+... 11: "B-product",
+... 12: "I-product",
+... }
+>>> label2id = {
+... "O": 0,
+... "B-corporation": 1,
+... "I-corporation": 2,
+... "B-creative-work": 3,
+... "I-creative-work": 4,
+... "B-group": 5,
+... "I-group": 6,
+... "B-location": 7,
+... "I-location": 8,
+... "B-person": 9,
+... "I-person": 10,
+... "B-product": 11,
+... "I-product": 12,
+... }
+```
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load DistilBERT with [`AutoModelForTokenClassification`] along with the number of expected labels, and the label mappings:
+
+```py
+>>> from transformers import AutoModelForTokenClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForTokenClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=13, id2label=id2label, label2id=label2id
+... )
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the seqeval scores and save the training checkpoint.
+2. Pass the training arguments to [`Trainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_wnut_model",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=2,
+... weight_decay=0.01,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... load_best_model_at_end=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_wnut["train"],
+... eval_dataset=tokenized_wnut["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+If you aren't familiar with finetuning a model with Keras, take a look at the basic tutorial [here](../training#train-a-tensorflow-model-with-keras)!
+
+
+To finetune a model in TensorFlow, start by setting up an optimizer function, learning rate schedule, and some training hyperparameters:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_train_epochs = 3
+>>> num_train_steps = (len(tokenized_wnut["train"]) // batch_size) * num_train_epochs
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=2e-5,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=0.01,
+... num_warmup_steps=0,
+... )
+```
+
+Then you can load DistilBERT with [`TFAutoModelForTokenClassification`] along with the number of expected labels, and the label mappings:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=13, id2label=id2label, label2id=label2id
+... )
+```
+
+Convert your datasets to the `tf.data.Dataset` format with [`~transformers.TFPreTrainedModel.prepare_tf_dataset`]:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_wnut["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_wnut["validation"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+Configure the model for training with [`compile`](https://keras.io/api/models/model_training_apis/#compile-method). Note that Transformers models all have a default task-relevant loss function, so you don't need to specify one unless you want to:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+The last two things to setup before you start training is to compute the seqeval scores from the predictions, and provide a way to push your model to the Hub. Both are done by using [Keras callbacks](../main_classes/keras_callbacks).
+
+Pass your `compute_metrics` function to [`~transformers.KerasMetricCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+Specify where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_wnut_model",
+... tokenizer=tokenizer,
+... )
+```
+
+Then bundle your callbacks together:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+Finally, you're ready to start training your model! Call [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) with your training and validation datasets, the number of epochs, and your callbacks to finetune the model:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=callbacks)
+```
+
+Once training is completed, your model is automatically uploaded to the Hub so everyone can use it!
+
+
+
+
+
+For a more in-depth example of how to finetune a model for token classification, take a look at the corresponding
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb)
+or [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification-tf.ipynb).
+
+
+
+## Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Grab some text you'd like to run inference on:
+
+```py
+>>> text = "The Golden State Warriors are an American professional basketball team based in San Francisco."
+```
+
+The simplest way to try out your finetuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for NER with your model, and pass your text to it:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("ner", model="stevhliu/my_awesome_wnut_model")
+>>> classifier(text)
+[{'entity': 'B-location',
+ 'score': 0.42658573,
+ 'index': 2,
+ 'word': 'golden',
+ 'start': 4,
+ 'end': 10},
+ {'entity': 'I-location',
+ 'score': 0.35856336,
+ 'index': 3,
+ 'word': 'state',
+ 'start': 11,
+ 'end': 16},
+ {'entity': 'B-group',
+ 'score': 0.3064001,
+ 'index': 4,
+ 'word': 'warriors',
+ 'start': 17,
+ 'end': 25},
+ {'entity': 'B-location',
+ 'score': 0.65523505,
+ 'index': 13,
+ 'word': 'san',
+ 'start': 80,
+ 'end': 83},
+ {'entity': 'B-location',
+ 'score': 0.4668663,
+ 'index': 14,
+ 'word': 'francisco',
+ 'start': 84,
+ 'end': 93}]
+```
+
+You can also manually replicate the results of the `pipeline` if you'd like:
+
+
+
+Tokenize the text and return PyTorch tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+```
+
+Pass your inputs to the model and return the `logits`:
+
+```py
+>>> from transformers import AutoModelForTokenClassification
+
+>>> model = AutoModelForTokenClassification.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+Get the class with the highest probability, and use the model's `id2label` mapping to convert it to a text label:
+
+```py
+>>> predictions = torch.argmax(logits, dim=2)
+>>> predicted_token_class = [model.config.id2label[t.item()] for t in predictions[0]]
+>>> predicted_token_class
+['O',
+ 'O',
+ 'B-location',
+ 'I-location',
+ 'B-group',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'B-location',
+ 'B-location',
+ 'O',
+ 'O']
+```
+
+
+Tokenize the text and return TensorFlow tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+```
+
+Pass your inputs to the model and return the `logits`:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> logits = model(**inputs).logits
+```
+
+Get the class with the highest probability, and use the model's `id2label` mapping to convert it to a text label:
+
+```py
+>>> predicted_token_class_ids = tf.math.argmax(logits, axis=-1)
+>>> predicted_token_class = [model.config.id2label[t] for t in predicted_token_class_ids[0].numpy().tolist()]
+>>> predicted_token_class
+['O',
+ 'O',
+ 'B-location',
+ 'I-location',
+ 'B-group',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'B-location',
+ 'B-location',
+ 'O',
+ 'O']
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/translation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/translation.md
new file mode 100644
index 0000000000000000000000000000000000000000..922cdc7241176a22faf030e37ea21b5b7f467ba3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/translation.md
@@ -0,0 +1,409 @@
+
+
+# Translation
+
+[[open-in-colab]]
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/translation).
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate sacrebleu
+```
+
+We encourage you to login to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load OPUS Books dataset
+
+Start by loading the English-French subset of the [OPUS Books](https://huggingface.co/datasets/opus_books) dataset from the 🤗 Datasets library:
+
+```py
+>>> from datasets import load_dataset
+
+>>> books = load_dataset("opus_books", "en-fr")
+```
+
+Split the dataset into a train and test set with the [`~datasets.Dataset.train_test_split`] method:
+
+```py
+>>> books = books["train"].train_test_split(test_size=0.2)
+```
+
+Then take a look at an example:
+
+```py
+>>> books["train"][0]
+{'id': '90560',
+ 'translation': {'en': 'But this lofty plateau measured only a few fathoms, and soon we reentered Our Element.',
+ 'fr': 'Mais ce plateau élevé ne mesurait que quelques toises, et bientôt nous fûmes rentrés dans notre élément.'}}
+```
+
+`translation`: an English and French translation of the text.
+
+## Preprocess
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint)
+```
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint, return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load a evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load the [SacreBLEU](https://huggingface.co/spaces/evaluate-metric/sacrebleu) metric (see the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about how to load and compute a metric):
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("sacrebleu")
+```
+
+Then create a function that passes your predictions and labels to [`~evaluate.EvaluationModule.compute`] to calculate the SacreBLEU score:
+
+```py
+>>> import numpy as np
+
+
+>>> def postprocess_text(preds, labels):
+... preds = [pred.strip() for pred in preds]
+... labels = [[label.strip()] for label in labels]
+
+... return preds, labels
+
+
+>>> def compute_metrics(eval_preds):
+... preds, labels = eval_preds
+... if isinstance(preds, tuple):
+... preds = preds[0]
+... decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
+
+... labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+... decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+... decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
+
+... result = metric.compute(predictions=decoded_preds, references=decoded_labels)
+... result = {"bleu": result["score"]}
+
+... prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in preds]
+... result["gen_len"] = np.mean(prediction_lens)
+... result = {k: round(v, 4) for k, v in result.items()}
+... return result
+```
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you setup your training.
+
+## Train
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load T5 with [`AutoModelForSeq2SeqLM`]:
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM, Seq2SeqTrainingArguments, Seq2SeqTrainer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`Seq2SeqTrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the SacreBLEU metric and save the training checkpoint.
+2. Pass the training arguments to [`Seq2SeqTrainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = Seq2SeqTrainingArguments(
+... output_dir="my_awesome_opus_books_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... weight_decay=0.01,
+... save_total_limit=3,
+... num_train_epochs=2,
+... predict_with_generate=True,
+... fp16=True, #change to bf16=True for XPU
+... push_to_hub=True,
+... )
+
+>>> trainer = Seq2SeqTrainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_books["train"],
+... eval_dataset=tokenized_books["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+If you aren't familiar with finetuning a model with Keras, take a look at the basic tutorial [here](../training#train-a-tensorflow-model-with-keras)!
+
+
+To finetune a model in TensorFlow, start by setting up an optimizer function, learning rate schedule, and some training hyperparameters:
+
+```py
+>>> from transformers import AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+Then you can load T5 with [`TFAutoModelForSeq2SeqLM`]:
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+Convert your datasets to the `tf.data.Dataset` format with [`~transformers.TFPreTrainedModel.prepare_tf_dataset`]:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_books["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... tokenized_books["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+Configure the model for training with [`compile`](https://keras.io/api/models/model_training_apis/#compile-method). Note that Transformers models all have a default task-relevant loss function, so you don't need to specify one unless you want to:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+The last two things to setup before you start training is to compute the SacreBLEU metric from the predictions, and provide a way to push your model to the Hub. Both are done by using [Keras callbacks](../main_classes/keras_callbacks).
+
+Pass your `compute_metrics` function to [`~transformers.KerasMetricCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_test_set)
+```
+
+Specify where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_opus_books_model",
+... tokenizer=tokenizer,
+... )
+```
+
+Then bundle your callbacks together:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+Finally, you're ready to start training your model! Call [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) with your training and validation datasets, the number of epochs, and your callbacks to finetune the model:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=callbacks)
+```
+
+Once training is completed, your model is automatically uploaded to the Hub so everyone can use it!
+
+
+
+
+
+For a more in-depth example of how to finetune a model for translation, take a look at the corresponding
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation.ipynb)
+or [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation-tf.ipynb).
+
+
+
+## Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Come up with some text you'd like to translate to another language. For T5, you need to prefix your input depending on the task you're working on. For translation from English to French, you should prefix your input as shown below:
+
+```py
+>>> text = "translate English to French: Legumes share resources with nitrogen-fixing bacteria."
+```
+
+The simplest way to try out your finetuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for translation with your model, and pass your text to it:
+
+```py
+>>> from transformers import pipeline
+
+# Change `xx` to the language of the input and `yy` to the language of the desired output.
+# Examples: "en" for English, "fr" for French, "de" for German, "es" for Spanish, "zh" for Chinese, etc; translation_en_to_fr translates English to French
+# You can view all the lists of languages here - https://huggingface.co/languages
+>>> translator = pipeline("translation_xx_to_yy", model="username/my_awesome_opus_books_model")
+>>> translator(text)
+[{'translation_text': 'Legumes partagent des ressources avec des bactéries azotantes.'}]
+```
+
+You can also manually replicate the results of the `pipeline` if you'd like:
+
+
+
+Tokenize the text and return the `input_ids` as PyTorch tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_opus_books_model")
+>>> inputs = tokenizer(text, return_tensors="pt").input_ids
+```
+
+Use the [`~generation.GenerationMixin.generate`] method to create the translation. For more details about the different text generation strategies and parameters for controlling generation, check out the [Text Generation](../main_classes/text_generation) API.
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("username/my_awesome_opus_books_model")
+>>> outputs = model.generate(inputs, max_new_tokens=40, do_sample=True, top_k=30, top_p=0.95)
+```
+
+Decode the generated token ids back into text:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'Les lignées partagent des ressources avec des bactéries enfixant l'azote.'
+```
+
+
+Tokenize the text and return the `input_ids` as TensorFlow tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_opus_books_model")
+>>> inputs = tokenizer(text, return_tensors="tf").input_ids
+```
+
+Use the [`~transformers.generation_tf_utils.TFGenerationMixin.generate`] method to create the translation. For more details about the different text generation strategies and parameters for controlling generation, check out the [Text Generation](../main_classes/text_generation) API.
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained("username/my_awesome_opus_books_model")
+>>> outputs = model.generate(inputs, max_new_tokens=40, do_sample=True, top_k=30, top_p=0.95)
+```
+
+Decode the generated token ids back into text:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'Les lugumes partagent les ressources avec des bactéries fixatrices d'azote.'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/video_classification.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/video_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..c268de1786bdc5453b38f899d89d39f5ddd6e453
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/video_classification.md
@@ -0,0 +1,516 @@
+
+
+# Video classification
+
+[[open-in-colab]]
+
+Video classification is the task of assigning a label or class to an entire video. Videos are expected to have only one class for each video. Video classification models take a video as input and return a prediction about which class the video belongs to. These models can be used to categorize what a video is all about. A real-world application of video classification is action / activity recognition, which is useful for fitness applications. It is also helpful for vision-impaired individuals, especially when they are commuting.
+
+This guide will show you how to:
+
+1. Fine-tune [VideoMAE](https://huggingface.co/docs/transformers/main/en/model_doc/videomae) on a subset of the [UCF101](https://www.crcv.ucf.edu/data/UCF101.php) dataset.
+2. Use your fine-tuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/video-classification).
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install -q pytorchvideo transformers evaluate
+```
+
+You will use [PyTorchVideo](https://pytorchvideo.org/) (dubbed `pytorchvideo`) to process and prepare the videos.
+
+We encourage you to log in to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to log in:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load UCF101 dataset
+
+Start by loading a subset of the [UCF-101 dataset](https://www.crcv.ucf.edu/data/UCF101.php). This will give you a chance to experiment and make sure everything works before spending more time training on the full dataset.
+
+```py
+>>> from huggingface_hub import hf_hub_download
+
+>>> hf_dataset_identifier = "sayakpaul/ucf101-subset"
+>>> filename = "UCF101_subset.tar.gz"
+>>> file_path = hf_hub_download(repo_id=hf_dataset_identifier, filename=filename, repo_type="dataset")
+```
+
+After the subset has been downloaded, you need to extract the compressed archive:
+
+```py
+>>> import tarfile
+
+>>> with tarfile.open(file_path) as t:
+... t.extractall(".")
+```
+
+At a high level, the dataset is organized like so:
+
+```bash
+UCF101_subset/
+ train/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+ val/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+ test/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+```
+
+You can then count the number of total videos.
+
+```py
+>>> import pathlib
+>>> dataset_root_path = "UCF101_subset"
+>>> dataset_root_path = pathlib.Path(dataset_root_path)
+```
+
+```py
+>>> video_count_train = len(list(dataset_root_path.glob("train/*/*.avi")))
+>>> video_count_val = len(list(dataset_root_path.glob("val/*/*.avi")))
+>>> video_count_test = len(list(dataset_root_path.glob("test/*/*.avi")))
+>>> video_total = video_count_train + video_count_val + video_count_test
+>>> print(f"Total videos: {video_total}")
+```
+
+```py
+>>> all_video_file_paths = (
+... list(dataset_root_path.glob("train/*/*.avi"))
+... + list(dataset_root_path.glob("val/*/*.avi"))
+... + list(dataset_root_path.glob("test/*/*.avi"))
+... )
+>>> all_video_file_paths[:5]
+```
+
+The (`sorted`) video paths appear like so:
+
+```bash
+...
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g07_c04.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g07_c06.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g08_c01.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g09_c02.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g09_c06.avi'
+...
+```
+
+You will notice that there are video clips belonging to the same group / scene where group is denoted by `g` in the video file paths. `v_ApplyEyeMakeup_g07_c04.avi` and `v_ApplyEyeMakeup_g07_c06.avi`, for example.
+
+For the validation and evaluation splits, you wouldn't want to have video clips from the same group / scene to prevent [data leakage](https://www.kaggle.com/code/alexisbcook/data-leakage). The subset that you are using in this tutorial takes this information into account.
+
+Next up, you will derive the set of labels present in the dataset. Also, create two dictionaries that'll be helpful when initializing the model:
+
+* `label2id`: maps the class names to integers.
+* `id2label`: maps the integers to class names.
+
+```py
+>>> class_labels = sorted({str(path).split("/")[2] for path in all_video_file_paths})
+>>> label2id = {label: i for i, label in enumerate(class_labels)}
+>>> id2label = {i: label for label, i in label2id.items()}
+
+>>> print(f"Unique classes: {list(label2id.keys())}.")
+
+# Unique classes: ['ApplyEyeMakeup', 'ApplyLipstick', 'Archery', 'BabyCrawling', 'BalanceBeam', 'BandMarching', 'BaseballPitch', 'Basketball', 'BasketballDunk', 'BenchPress'].
+```
+
+There are 10 unique classes. For each class, there are 30 videos in the training set.
+
+## Load a model to fine-tune
+
+Instantiate a video classification model from a pretrained checkpoint and its associated image processor. The model's encoder comes with pre-trained parameters, and the classification head is randomly initialized. The image processor will come in handy when writing the preprocessing pipeline for our dataset.
+
+```py
+>>> from transformers import VideoMAEImageProcessor, VideoMAEForVideoClassification
+
+>>> model_ckpt = "MCG-NJU/videomae-base"
+>>> image_processor = VideoMAEImageProcessor.from_pretrained(model_ckpt)
+>>> model = VideoMAEForVideoClassification.from_pretrained(
+... model_ckpt,
+... label2id=label2id,
+... id2label=id2label,
+... ignore_mismatched_sizes=True, # provide this in case you're planning to fine-tune an already fine-tuned checkpoint
+... )
+```
+
+While the model is loading, you might notice the following warning:
+
+```bash
+Some weights of the model checkpoint at MCG-NJU/videomae-base were not used when initializing VideoMAEForVideoClassification: [..., 'decoder.decoder_layers.1.attention.output.dense.bias', 'decoder.decoder_layers.2.attention.attention.key.weight']
+- This IS expected if you are initializing VideoMAEForVideoClassification from the checkpoint of a model trained on another task or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).
+- This IS NOT expected if you are initializing VideoMAEForVideoClassification from the checkpoint of a model that you expect to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model).
+Some weights of VideoMAEForVideoClassification were not initialized from the model checkpoint at MCG-NJU/videomae-base and are newly initialized: ['classifier.bias', 'classifier.weight']
+You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.
+```
+
+The warning is telling us we are throwing away some weights (e.g. the weights and bias of the `classifier` layer) and randomly initializing some others (the weights and bias of a new `classifier` layer). This is expected in this case, because we are adding a new head for which we don't have pretrained weights, so the library warns us we should fine-tune this model before using it for inference, which is exactly what we are going to do.
+
+**Note** that [this checkpoint](https://huggingface.co/MCG-NJU/videomae-base-finetuned-kinetics) leads to better performance on this task as the checkpoint was obtained fine-tuning on a similar downstream task having considerable domain overlap. You can check out [this checkpoint](https://huggingface.co/sayakpaul/videomae-base-finetuned-kinetics-finetuned-ucf101-subset) which was obtained by fine-tuning `MCG-NJU/videomae-base-finetuned-kinetics`.
+
+## Prepare the datasets for training
+
+For preprocessing the videos, you will leverage the [PyTorchVideo library](https://pytorchvideo.org/). Start by importing the dependencies we need.
+
+```py
+>>> import pytorchvideo.data
+
+>>> from pytorchvideo.transforms import (
+... ApplyTransformToKey,
+... Normalize,
+... RandomShortSideScale,
+... RemoveKey,
+... ShortSideScale,
+... UniformTemporalSubsample,
+... )
+
+>>> from torchvision.transforms import (
+... Compose,
+... Lambda,
+... RandomCrop,
+... RandomHorizontalFlip,
+... Resize,
+... )
+```
+
+For the training dataset transformations, use a combination of uniform temporal subsampling, pixel normalization, random cropping, and random horizontal flipping. For the validation and evaluation dataset transformations, keep the same transformation chain except for random cropping and horizontal flipping. To learn more about the details of these transformations check out the [official documentation of PyTorchVideo](https://pytorchvideo.org).
+
+Use the `image_processor` associated with the pre-trained model to obtain the following information:
+
+* Image mean and standard deviation with which the video frame pixels will be normalized.
+* Spatial resolution to which the video frames will be resized.
+
+Start by defining some constants.
+
+```py
+>>> mean = image_processor.image_mean
+>>> std = image_processor.image_std
+>>> if "shortest_edge" in image_processor.size:
+... height = width = image_processor.size["shortest_edge"]
+>>> else:
+... height = image_processor.size["height"]
+... width = image_processor.size["width"]
+>>> resize_to = (height, width)
+
+>>> num_frames_to_sample = model.config.num_frames
+>>> sample_rate = 4
+>>> fps = 30
+>>> clip_duration = num_frames_to_sample * sample_rate / fps
+```
+
+Now, define the dataset-specific transformations and the datasets respectively. Starting with the training set:
+
+```py
+>>> train_transform = Compose(
+... [
+... ApplyTransformToKey(
+... key="video",
+... transform=Compose(
+... [
+... UniformTemporalSubsample(num_frames_to_sample),
+... Lambda(lambda x: x / 255.0),
+... Normalize(mean, std),
+... RandomShortSideScale(min_size=256, max_size=320),
+... RandomCrop(resize_to),
+... RandomHorizontalFlip(p=0.5),
+... ]
+... ),
+... ),
+... ]
+... )
+
+>>> train_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "train"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("random", clip_duration),
+... decode_audio=False,
+... transform=train_transform,
+... )
+```
+
+The same sequence of workflow can be applied to the validation and evaluation sets:
+
+```py
+>>> val_transform = Compose(
+... [
+... ApplyTransformToKey(
+... key="video",
+... transform=Compose(
+... [
+... UniformTemporalSubsample(num_frames_to_sample),
+... Lambda(lambda x: x / 255.0),
+... Normalize(mean, std),
+... Resize(resize_to),
+... ]
+... ),
+... ),
+... ]
+... )
+
+>>> val_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "val"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("uniform", clip_duration),
+... decode_audio=False,
+... transform=val_transform,
+... )
+
+>>> test_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "test"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("uniform", clip_duration),
+... decode_audio=False,
+... transform=val_transform,
+... )
+```
+
+**Note**: The above dataset pipelines are taken from the [official PyTorchVideo example](https://pytorchvideo.org/docs/tutorial_classification#dataset). We're using the [`pytorchvideo.data.Ucf101()`](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html#pytorchvideo.data.Ucf101) function because it's tailored for the UCF-101 dataset. Under the hood, it returns a [`pytorchvideo.data.labeled_video_dataset.LabeledVideoDataset`](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html#pytorchvideo.data.LabeledVideoDataset) object. `LabeledVideoDataset` class is the base class for all things video in the PyTorchVideo dataset. So, if you want to use a custom dataset not supported off-the-shelf by PyTorchVideo, you can extend the `LabeledVideoDataset` class accordingly. Refer to the `data` API [documentation to](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html) learn more. Also, if your dataset follows a similar structure (as shown above), then using the `pytorchvideo.data.Ucf101()` should work just fine.
+
+You can access the `num_videos` argument to know the number of videos in the dataset.
+
+```py
+>>> print(train_dataset.num_videos, val_dataset.num_videos, test_dataset.num_videos)
+# (300, 30, 75)
+```
+
+## Visualize the preprocessed video for better debugging
+
+```py
+>>> import imageio
+>>> import numpy as np
+>>> from IPython.display import Image
+
+>>> def unnormalize_img(img):
+... """Un-normalizes the image pixels."""
+... img = (img * std) + mean
+... img = (img * 255).astype("uint8")
+... return img.clip(0, 255)
+
+>>> def create_gif(video_tensor, filename="sample.gif"):
+... """Prepares a GIF from a video tensor.
+...
+... The video tensor is expected to have the following shape:
+... (num_frames, num_channels, height, width).
+... """
+... frames = []
+... for video_frame in video_tensor:
+... frame_unnormalized = unnormalize_img(video_frame.permute(1, 2, 0).numpy())
+... frames.append(frame_unnormalized)
+... kargs = {"duration": 0.25}
+... imageio.mimsave(filename, frames, "GIF", **kargs)
+... return filename
+
+>>> def display_gif(video_tensor, gif_name="sample.gif"):
+... """Prepares and displays a GIF from a video tensor."""
+... video_tensor = video_tensor.permute(1, 0, 2, 3)
+... gif_filename = create_gif(video_tensor, gif_name)
+... return Image(filename=gif_filename)
+
+>>> sample_video = next(iter(train_dataset))
+>>> video_tensor = sample_video["video"]
+>>> display_gif(video_tensor)
+```
+
+
+
+
+
+
`".
+
+In this guide, we provide a brief overview of video LMs and show how to use them with Transformers for inference.
+
+To begin with, there are multiple types of video LMs:
+- base models used for fine-tuning
+- chat fine-tuned models for conversation
+- instruction fine-tuned models
+
+This guide focuses on inference with an instruction-tuned model, [llava-hf/llava-interleave-qwen-7b-hf](https://huggingface.co/llava-hf/llava-interleave-qwen-7b-hf) which can take in interleaved data. Alternatively, you can try [llava-interleave-qwen-0.5b-hf](https://huggingface.co/llava-hf/llava-interleave-qwen-0.5b-hf) if your hardware doesn't allow running a 7B model.
+
+Let's begin installing the dependencies.
+
+```bash
+pip install -q transformers accelerate flash_attn
+```
+
+Let's initialize the model and the processor.
+
+```python
+from transformers import LlavaProcessor, LlavaForConditionalGeneration
+import torch
+model_id = "llava-hf/llava-interleave-qwen-0.5b-hf"
+
+processor = LlavaProcessor.from_pretrained(model_id)
+
+model = LlavaForConditionalGeneration.from_pretrained(model_id, torch_dtype=torch.float16)
+model.to("cuda") # can also be xpu, mps, npu etc. depending on your hardware accelerator
+```
+
+Some models directly consume the `` token, and others accept `` tokens equal to the number of sampled frames. This model handles videos in the latter fashion. We will write a simple utility to handle image tokens, and another utility to get a video from a url and sample frames from it.
+
+```python
+import uuid
+import requests
+import cv2
+from PIL import Image
+
+def replace_video_with_images(text, frames):
+ return text.replace("", "" * frames)
+
+def sample_frames(url, num_frames):
+
+ response = requests.get(url)
+ path_id = str(uuid.uuid4())
+
+ path = f"./{path_id}.mp4"
+
+ with open(path, "wb") as f:
+ f.write(response.content)
+
+ video = cv2.VideoCapture(path)
+ total_frames = int(video.get(cv2.CAP_PROP_FRAME_COUNT))
+ interval = total_frames // num_frames
+ frames = []
+ for i in range(total_frames):
+ ret, frame = video.read()
+ pil_img = Image.fromarray(cv2.cvtColor(frame, cv2.COLOR_BGR2RGB))
+ if not ret:
+ continue
+ if i % interval == 0:
+ frames.append(pil_img)
+ video.release()
+ return frames[:num_frames]
+```
+
+Let's get our inputs. We will sample frames and concatenate them.
+
+```python
+video_1 = "https://huggingface.co/spaces/merve/llava-interleave/resolve/main/cats_1.mp4"
+video_2 = "https://huggingface.co/spaces/merve/llava-interleave/resolve/main/cats_2.mp4"
+
+video_1 = sample_frames(video_1, 6)
+video_2 = sample_frames(video_2, 6)
+
+videos = video_1 + video_2
+
+videos
+
+# [,
+# ,
+# , ...]
+```
+
+Both videos have cats.
+
+
+
+Now we can preprocess the inputs.
+
+This model has a prompt template that looks like following. First, we'll put all the sampled frames into one list. Since we have eight frames in each video, we will insert 12 `` tokens to our prompt. Add `assistant` at the end of the prompt to trigger the model to give answers. Then we can preprocess.
+
+```python
+user_prompt = "Are these two cats in these two videos doing the same thing?"
+toks = "" * 12
+prompt = "<|im_start|>user"+ toks + f"\n{user_prompt}<|im_end|><|im_start|>assistant"
+inputs = processor(text=prompt, images=videos, return_tensors="pt").to(model.device, model.dtype)
+```
+
+We can now call [`~GenerationMixin.generate`] for inference. The model outputs the question in our input and answer, so we only take the text after the prompt and `assistant` part from the model output.
+
+```python
+output = model.generate(**inputs, max_new_tokens=100, do_sample=False)
+print(processor.decode(output[0][2:], skip_special_tokens=True)[len(user_prompt)+10:])
+
+# The first cat is shown in a relaxed state, with its eyes closed and a content expression, while the second cat is shown in a more active state, with its mouth open wide, possibly in a yawn or a vocalization.
+
+
+```
+
+And voila!
+
+To learn more about chat templates and token streaming for video-text-to-text models, refer to the [image-text-to-text](../tasks/image_text_to_text) task guide because these models work similarly.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/visual_question_answering.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/visual_question_answering.md
new file mode 100644
index 0000000000000000000000000000000000000000..87dbfb751bfa9872fa75bdd7834a1ae23b27a698
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tasks/visual_question_answering.md
@@ -0,0 +1,401 @@
+
+
+# Visual Question Answering
+
+[[open-in-colab]]
+
+Visual Question Answering (VQA) is the task of answering open-ended questions based on an image.
+The input to models supporting this task is typically a combination of an image and a question, and the output is an
+answer expressed in natural language.
+
+Some noteworthy use case examples for VQA include:
+* Accessibility applications for visually impaired individuals.
+* Education: posing questions about visual materials presented in lectures or textbooks. VQA can also be utilized in interactive museum exhibits or historical sites.
+* Customer service and e-commerce: VQA can enhance user experience by letting users ask questions about products.
+* Image retrieval: VQA models can be used to retrieve images with specific characteristics. For example, the user can ask "Is there a dog?" to find all images with dogs from a set of images.
+
+In this guide you'll learn how to:
+
+- Fine-tune a classification VQA model, specifically [ViLT](../model_doc/vilt), on the [`Graphcore/vqa` dataset](https://huggingface.co/datasets/Graphcore/vqa).
+- Use your fine-tuned ViLT for inference.
+- Run zero-shot VQA inference with a generative model, like BLIP-2.
+
+## Fine-tuning ViLT
+
+ViLT model incorporates text embeddings into a Vision Transformer (ViT), allowing it to have a minimal design for
+Vision-and-Language Pre-training (VLP). This model can be used for several downstream tasks. For the VQA task, a classifier
+head is placed on top (a linear layer on top of the final hidden state of the `[CLS]` token) and randomly initialized.
+Visual Question Answering is thus treated as a **classification problem**.
+
+More recent models, such as BLIP, BLIP-2, and InstructBLIP, treat VQA as a generative task. Later in this guide we
+illustrate how to use them for zero-shot VQA inference.
+
+Before you begin, make sure you have all the necessary libraries installed.
+
+```bash
+pip install -q transformers datasets
+```
+
+We encourage you to share your model with the community. Log in to your Hugging Face account to upload it to the 🤗 Hub.
+When prompted, enter your token to log in:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+Let's define the model checkpoint as a global variable.
+
+```py
+>>> model_checkpoint = "dandelin/vilt-b32-mlm"
+```
+
+## Load the data
+
+For illustration purposes, in this guide we use a very small sample of the annotated visual question answering `Graphcore/vqa` dataset.
+You can find the full dataset on [🤗 Hub](https://huggingface.co/datasets/Graphcore/vqa).
+
+As an alternative to the [`Graphcore/vqa` dataset](https://huggingface.co/datasets/Graphcore/vqa), you can download the
+same data manually from the official [VQA dataset page](https://visualqa.org/download.html). If you prefer to follow the
+tutorial with your custom data, check out how to [Create an image dataset](https://huggingface.co/docs/datasets/image_dataset#loading-script)
+guide in the 🤗 Datasets documentation.
+
+Let's load the first 200 examples from the validation split and explore the dataset's features:
+
+```python
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("Graphcore/vqa", split="validation[:200]")
+>>> dataset
+Dataset({
+ features: ['question', 'question_type', 'question_id', 'image_id', 'answer_type', 'label'],
+ num_rows: 200
+})
+```
+
+Let's take a look at an example to understand the dataset's features:
+
+```py
+>>> dataset[0]
+{'question': 'Where is he looking?',
+ 'question_type': 'none of the above',
+ 'question_id': 262148000,
+ 'image_id': '/root/.cache/huggingface/datasets/downloads/extracted/ca733e0e000fb2d7a09fbcc94dbfe7b5a30750681d0e965f8e0a23b1c2f98c75/val2014/COCO_val2014_000000262148.jpg',
+ 'answer_type': 'other',
+ 'label': {'ids': ['at table', 'down', 'skateboard', 'table'],
+ 'weights': [0.30000001192092896,
+ 1.0,
+ 0.30000001192092896,
+ 0.30000001192092896]}}
+```
+
+The features relevant to the task include:
+* `question`: the question to be answered from the image
+* `image_id`: the path to the image the question refers to
+* `label`: the annotations
+
+We can remove the rest of the features as they won't be necessary:
+
+```py
+>>> dataset = dataset.remove_columns(['question_type', 'question_id', 'answer_type'])
+```
+
+As you can see, the `label` feature contains several answers to the same question (called `ids` here) collected by different human annotators.
+This is because the answer to a question can be subjective. In this case, the question is "where is he looking?". Some people
+annotated this with "down", others with "at table", another one with "skateboard", etc.
+
+Take a look at the image and consider which answer would you give:
+
+```python
+>>> from PIL import Image
+
+>>> image = Image.open(dataset[0]['image_id'])
+>>> image
+```
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Before you go further, it is good to have some basic knowledge of the original Transformer architecture. Knowing how encoders, decoders, and attention work will aid you in understanding how different Transformer models work. If you're just getting started or need a refresher, check out our [course](https://huggingface.co/course/chapter1/4?fw=pt) for more information!
+
+
+
+## Speech and audio
+
+[Wav2Vec2](model_doc/wav2vec2) is a self-supervised model pretrained on unlabeled speech data and finetuned on labeled data for audio classification and automatic speech recognition.
+
+
+
+
+
+A third approach mixes Transformers with convolutions (for example, [Convolutional Vision Transformer](model_doc/cvt) or [LeViT](model_doc/levit)). We won't discuss those because they just combine the two approaches we examine here.
+
+
+
+ViT and ConvNeXT are commonly used for image classification, but for other vision tasks like object detection, segmentation, and depth estimation, we'll look at DETR, Mask2Former and GLPN, respectively; these models are better suited for those tasks.
+
+### Image classification
+
+ViT and ConvNeXT can both be used for image classification; the main difference is that ViT uses an attention mechanism while ConvNeXT uses convolutions.
+
+#### Transformer
+
+[ViT](model_doc/vit) replaces convolutions entirely with a pure Transformer architecture. If you're familiar with the original Transformer, then you're already most of the way toward understanding ViT.
+
+
+
+
+
+This section briefly explains convolutions, but it'd be helpful to have a prior understanding of how they change an image's shape and size. If you're unfamiliar with convolutions, check out the [Convolution Neural Networks chapter](https://github.com/fastai/fastbook/blob/master/13_convolutions.ipynb) from the fastai book!
+
+
+
+[ConvNeXT](model_doc/convnext) is a CNN architecture that adopts new and modern network designs to improve performance. However, convolutions are still at the core of the model. From a high-level perspective, a [convolution](glossary#convolution) is an operation where a smaller matrix (*kernel*) is multiplied by a small window of the image pixels. It computes some features from it, such as a particular texture or curvature of a line. Then it slides over to the next window of pixels; the distance the convolution travels is known as the *stride*.
+
+
+
+
A basic convolution without padding or stride, taken from A guide to convolution arithmetic for deep learning.
+
+You can feed this output to another convolutional layer, and with each successive layer, the network learns more complex and abstract things like hotdogs or rockets. Between convolutional layers, it is common to add a pooling layer to reduce dimensionality and make the model more robust to variations of a feature's position.
+
+
+
+
+
+
+
+
+
+
+
+💡 Notice how easy it is to use BERT for different tasks once it's been pretrained. You only need to add a specific head to the pretrained model to manipulate the hidden states into your desired output!
+
+
+
+### Text generation
+
+[GPT-2](model_doc/gpt2) is a decoder-only model pretrained on a large amount of text. It can generate convincing (though not always true!) text given a prompt and complete other NLP tasks like question answering despite not being explicitly trained to.
+
+
+
+
+
+For more information about text generation, check out the [text generation strategies](generation_strategies) guide!
+
+
+
+### Summarization
+
+Encoder-decoder models like [BART](model_doc/bart) and [T5](model_doc/t5) are designed for the sequence-to-sequence pattern of a summarization task. We'll explain how BART works in this section, and then you can try finetuning T5 at the end.
+
+
+
+
+
+For more information about text generation, check out the [text generation strategies](generation_strategies) guide!
+
+
+
+### Translation
+
+Translation is another example of a sequence-to-sequence task, which means you can use an encoder-decoder model like [BART](model_doc/bart) or [T5](model_doc/t5) to do it. We'll explain how BART works in this section, and then you can try finetuning T5 at the end.
+
+BART adapts to translation by adding a separate randomly initialized encoder to map a source language to an input that can be decoded into the target language. This new encoder's embeddings are passed to the pretrained encoder instead of the original word embeddings. The source encoder is trained by updating the source encoder, positional embeddings, and input embeddings with the cross-entropy loss from the model output. The model parameters are frozen in this first step, and all the model parameters are trained together in the second step.
+
+BART has since been followed up by a multilingual version, mBART, intended for translation and pretrained on many different languages.
+
+Ready to try your hand at translation? Check out our complete [translation guide](tasks/translation) to learn how to finetune T5 and use it for inference!
+
+
+
+For more information about text generation, check out the [text generation strategies](generation_strategies) guide!
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/testing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/testing.md
new file mode 100644
index 0000000000000000000000000000000000000000..9e85f2248e16fc9b7498c47ce62c2586ca8d0d23
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/testing.md
@@ -0,0 +1,1333 @@
+
+
+# Testing
+
+
+Let's take a look at how 🤗 Transformers models are tested and how you can write new tests and improve the existing ones.
+
+There are 2 test suites in the repository:
+
+1. `tests` -- tests for the general API
+2. `examples` -- tests primarily for various applications that aren't part of the API
+
+## How transformers are tested
+
+1. Once a PR is submitted it gets tested with 9 CircleCi jobs. Every new commit to that PR gets retested. These jobs
+ are defined in this [config file](https://github.com/huggingface/transformers/tree/main/.circleci/config.yml), so that if needed you can reproduce the same
+ environment on your machine.
+
+ These CI jobs don't run `@slow` tests.
+
+2. There are 3 jobs run by [github actions](https://github.com/huggingface/transformers/actions):
+
+ - [torch hub integration](https://github.com/huggingface/transformers/tree/main/.github/workflows/github-torch-hub.yml): checks whether torch hub
+ integration works.
+
+ - [self-hosted (push)](https://github.com/huggingface/transformers/tree/main/.github/workflows/self-push.yml): runs fast tests on GPU only on commits on
+ `main`. It only runs if a commit on `main` has updated the code in one of the following folders: `src`,
+ `tests`, `.github` (to prevent running on added model cards, notebooks, etc.)
+
+ - [self-hosted runner](https://github.com/huggingface/transformers/tree/main/.github/workflows/self-scheduled.yml): runs normal and slow tests on GPU in
+ `tests` and `examples`:
+
+```bash
+RUN_SLOW=1 pytest tests/
+RUN_SLOW=1 pytest examples/
+```
+
+ The results can be observed [here](https://github.com/huggingface/transformers/actions).
+
+
+
+## Running tests
+
+
+
+### Choosing which tests to run
+
+This document goes into many details of how tests can be run. If after reading everything, you need even more details
+you will find them [here](https://docs.pytest.org/en/latest/usage.html).
+
+Here are some most useful ways of running tests.
+
+Run all:
+
+```console
+pytest
+```
+
+or:
+
+```bash
+make test
+```
+
+Note that the latter is defined as:
+
+```bash
+python -m pytest -n auto --dist=loadfile -s -v ./tests/
+```
+
+which tells pytest to:
+
+- run as many test processes as they are CPU cores (which could be too many if you don't have a ton of RAM!)
+- ensure that all tests from the same file will be run by the same test process
+- do not capture output
+- run in verbose mode
+
+
+
+### Getting the list of all tests
+
+All tests of the test suite:
+
+```bash
+pytest --collect-only -q
+```
+
+All tests of a given test file:
+
+```bash
+pytest tests/test_optimization.py --collect-only -q
+```
+
+### Run a specific test module
+
+To run an individual test module:
+
+```bash
+pytest tests/utils/test_logging.py
+```
+
+### Run specific tests
+
+Since unittest is used inside most of the tests, to run specific subtests you need to know the name of the unittest
+class containing those tests. For example, it could be:
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest::test_adam_w
+```
+
+Here:
+
+- `tests/test_optimization.py` - the file with tests
+- `OptimizationTest` - the name of the class
+- `test_adam_w` - the name of the specific test function
+
+If the file contains multiple classes, you can choose to run only tests of a given class. For example:
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest
+```
+
+will run all the tests inside that class.
+
+As mentioned earlier you can see what tests are contained inside the `OptimizationTest` class by running:
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest --collect-only -q
+```
+
+You can run tests by keyword expressions.
+
+To run only tests whose name contains `adam`:
+
+```bash
+pytest -k adam tests/test_optimization.py
+```
+
+Logical `and` and `or` can be used to indicate whether all keywords should match or either. `not` can be used to
+negate.
+
+To run all tests except those whose name contains `adam`:
+
+```bash
+pytest -k "not adam" tests/test_optimization.py
+```
+
+And you can combine the two patterns in one:
+
+```bash
+pytest -k "ada and not adam" tests/test_optimization.py
+```
+
+For example to run both `test_adafactor` and `test_adam_w` you can use:
+
+```bash
+pytest -k "test_adafactor or test_adam_w" tests/test_optimization.py
+```
+
+Note that we use `or` here, since we want either of the keywords to match to include both.
+
+If you want to include only tests that include both patterns, `and` is to be used:
+
+```bash
+pytest -k "test and ada" tests/test_optimization.py
+```
+
+### Run `accelerate` tests
+
+Sometimes you need to run `accelerate` tests on your models. For that you can just add `-m accelerate_tests` to your command, if let's say you want to run these tests on `OPT` run:
+
+```bash
+RUN_SLOW=1 pytest -m accelerate_tests tests/models/opt/test_modeling_opt.py
+```
+
+
+### Run documentation tests
+
+In order to test whether the documentation examples are correct, you should check that the `doctests` are passing.
+As an example, let's use [`WhisperModel.forward`'s docstring](https://github.com/huggingface/transformers/blob/1124d95dbb1a3512d3e80791d73d0f541d1d7e9f/src/transformers/models/whisper/modeling_whisper.py#L1591-L1609)
+
+```python
+r"""
+Returns:
+
+Example:
+ ```python
+ >>> import torch
+ >>> from transformers import WhisperModel, WhisperFeatureExtractor
+ >>> from datasets import load_dataset
+
+ >>> model = WhisperModel.from_pretrained("openai/whisper-base")
+ >>> feature_extractor = WhisperFeatureExtractor.from_pretrained("openai/whisper-base")
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> inputs = feature_extractor(ds[0]["audio"]["array"], return_tensors="pt")
+ >>> input_features = inputs.input_features
+ >>> decoder_input_ids = torch.tensor([[1, 1]]) * model.config.decoder_start_token_id
+ >>> last_hidden_state = model(input_features, decoder_input_ids=decoder_input_ids).last_hidden_state
+ >>> list(last_hidden_state.shape)
+ [1, 2, 512]
+ ```"""
+
+```
+
+Just run the following line to automatically test every docstring example in the desired file:
+```bash
+pytest --doctest-modules
+```
+If the file has a markdown extention, you should add the `--doctest-glob="*.md"` argument.
+
+### Run only modified tests
+
+You can run the tests related to the unstaged files or the current branch (according to Git) by using [pytest-picked](https://github.com/anapaulagomes/pytest-picked). This is a great way of quickly testing your changes didn't break
+anything, since it won't run the tests related to files you didn't touch.
+
+```bash
+pip install pytest-picked
+```
+
+```bash
+pytest --picked
+```
+
+All tests will be run from files and folders which are modified, but not yet committed.
+
+### Automatically rerun failed tests on source modification
+
+[pytest-xdist](https://github.com/pytest-dev/pytest-xdist) provides a very useful feature of detecting all failed
+tests, and then waiting for you to modify files and continuously re-rerun those failing tests until they pass while you
+fix them. So that you don't need to re start pytest after you made the fix. This is repeated until all tests pass after
+which again a full run is performed.
+
+```bash
+pip install pytest-xdist
+```
+
+To enter the mode: `pytest -f` or `pytest --looponfail`
+
+File changes are detected by looking at `looponfailroots` root directories and all of their contents (recursively).
+If the default for this value does not work for you, you can change it in your project by setting a configuration
+option in `setup.cfg`:
+
+```ini
+[tool:pytest]
+looponfailroots = transformers tests
+```
+
+or `pytest.ini`/``tox.ini`` files:
+
+```ini
+[pytest]
+looponfailroots = transformers tests
+```
+
+This would lead to only looking for file changes in the respective directories, specified relatively to the ini-file’s
+directory.
+
+[pytest-watch](https://github.com/joeyespo/pytest-watch) is an alternative implementation of this functionality.
+
+
+### Skip a test module
+
+If you want to run all test modules, except a few you can exclude them by giving an explicit list of tests to run. For
+example, to run all except `test_modeling_*.py` tests:
+
+```bash
+pytest *ls -1 tests/*py | grep -v test_modeling*
+```
+
+### Clearing state
+
+CI builds and when isolation is important (against speed), cache should be cleared:
+
+```bash
+pytest --cache-clear tests
+```
+
+### Running tests in parallel
+
+As mentioned earlier `make test` runs tests in parallel via `pytest-xdist` plugin (`-n X` argument, e.g. `-n 2`
+to run 2 parallel jobs).
+
+`pytest-xdist`'s `--dist=` option allows one to control how the tests are grouped. `--dist=loadfile` puts the
+tests located in one file onto the same process.
+
+Since the order of executed tests is different and unpredictable, if running the test suite with `pytest-xdist`
+produces failures (meaning we have some undetected coupled tests), use [pytest-replay](https://github.com/ESSS/pytest-replay) to replay the tests in the same order, which should help with then somehow
+reducing that failing sequence to a minimum.
+
+### Test order and repetition
+
+It's good to repeat the tests several times, in sequence, randomly, or in sets, to detect any potential
+inter-dependency and state-related bugs (tear down). And the straightforward multiple repetition is just good to detect
+some problems that get uncovered by randomness of DL.
+
+
+#### Repeat tests
+
+- [pytest-flakefinder](https://github.com/dropbox/pytest-flakefinder):
+
+```bash
+pip install pytest-flakefinder
+```
+
+And then run every test multiple times (50 by default):
+
+```bash
+pytest --flake-finder --flake-runs=5 tests/test_failing_test.py
+```
+
+
+
+This plugin doesn't work with `-n` flag from `pytest-xdist`.
+
+
+
+
+
+There is another plugin `pytest-repeat`, but it doesn't work with `unittest`.
+
+
+
+#### Run tests in a random order
+
+```bash
+pip install pytest-random-order
+```
+
+Important: the presence of `pytest-random-order` will automatically randomize tests, no configuration change or
+command line options is required.
+
+As explained earlier this allows detection of coupled tests - where one test's state affects the state of another. When
+`pytest-random-order` is installed it will print the random seed it used for that session, e.g:
+
+```bash
+pytest tests
+[...]
+Using --random-order-bucket=module
+Using --random-order-seed=573663
+```
+
+So that if the given particular sequence fails, you can reproduce it by adding that exact seed, e.g.:
+
+```bash
+pytest --random-order-seed=573663
+[...]
+Using --random-order-bucket=module
+Using --random-order-seed=573663
+```
+
+It will only reproduce the exact order if you use the exact same list of tests (or no list at all). Once you start to
+manually narrowing down the list you can no longer rely on the seed, but have to list them manually in the exact order
+they failed and tell pytest to not randomize them instead using `--random-order-bucket=none`, e.g.:
+
+```bash
+pytest --random-order-bucket=none tests/test_a.py tests/test_c.py tests/test_b.py
+```
+
+To disable the shuffling for all tests:
+
+```bash
+pytest --random-order-bucket=none
+```
+
+By default `--random-order-bucket=module` is implied, which will shuffle the files on the module levels. It can also
+shuffle on `class`, `package`, `global` and `none` levels. For the complete details please see its
+[documentation](https://github.com/jbasko/pytest-random-order).
+
+Another randomization alternative is: [`pytest-randomly`](https://github.com/pytest-dev/pytest-randomly). This
+module has a very similar functionality/interface, but it doesn't have the bucket modes available in
+`pytest-random-order`. It has the same problem of imposing itself once installed.
+
+### Look and feel variations
+
+#### pytest-sugar
+
+[pytest-sugar](https://github.com/Frozenball/pytest-sugar) is a plugin that improves the look-n-feel, adds a
+progressbar, and show tests that fail and the assert instantly. It gets activated automatically upon installation.
+
+```bash
+pip install pytest-sugar
+```
+
+To run tests without it, run:
+
+```bash
+pytest -p no:sugar
+```
+
+or uninstall it.
+
+
+
+#### Report each sub-test name and its progress
+
+For a single or a group of tests via `pytest` (after `pip install pytest-pspec`):
+
+```bash
+pytest --pspec tests/test_optimization.py
+```
+
+#### Instantly shows failed tests
+
+[pytest-instafail](https://github.com/pytest-dev/pytest-instafail) shows failures and errors instantly instead of
+waiting until the end of test session.
+
+```bash
+pip install pytest-instafail
+```
+
+```bash
+pytest --instafail
+```
+
+### To GPU or not to GPU
+
+On a GPU-enabled setup, to test in CPU-only mode add `CUDA_VISIBLE_DEVICES=""` for CUDA GPUs:
+
+```bash
+CUDA_VISIBLE_DEVICES="" pytest tests/utils/test_logging.py
+```
+
+or if you have multiple gpus, you can specify which one is to be used by `pytest`. For example, to use only the
+second gpu if you have gpus `0` and `1`, you can run:
+
+```bash
+CUDA_VISIBLE_DEVICES="1" pytest tests/utils/test_logging.py
+```
+
+For Intel GPUs, use `ZE_AFFINITY_MASK` instead of `CUDA_VISIBLE_DEVICES` in the above example.
+
+This is handy when you want to run different tasks on different GPUs.
+
+Some tests must be run on CPU-only, others on either CPU or GPU or TPU, yet others on multiple-GPUs. The following skip
+decorators are used to set the requirements of tests CPU/GPU/XPU/TPU-wise:
+
+- `require_torch` - this test will run only under torch
+- `require_torch_gpu` - as `require_torch` plus requires at least 1 GPU
+- `require_torch_multi_gpu` - as `require_torch` plus requires at least 2 GPUs
+- `require_torch_non_multi_gpu` - as `require_torch` plus requires 0 or 1 GPUs
+- `require_torch_up_to_2_gpus` - as `require_torch` plus requires 0 or 1 or 2 GPUs
+- `require_torch_xla` - as `require_torch` plus requires at least 1 TPU
+
+Let's depict the GPU requirements in the following table:
+
+
+| n gpus | decorator |
+|--------|--------------------------------|
+| `>= 0` | `@require_torch` |
+| `>= 1` | `@require_torch_gpu` |
+| `>= 2` | `@require_torch_multi_gpu` |
+| `< 2` | `@require_torch_non_multi_gpu` |
+| `< 3` | `@require_torch_up_to_2_gpus` |
+
+
+For example, here is a test that must be run only when there are 2 or more GPUs available and pytorch is installed:
+
+```python no-style
+@require_torch_multi_gpu
+def test_example_with_multi_gpu():
+```
+
+If a test requires `tensorflow` use the `require_tf` decorator. For example:
+
+```python no-style
+@require_tf
+def test_tf_thing_with_tensorflow():
+```
+
+These decorators can be stacked. For example, if a test is slow and requires at least one GPU under pytorch, here is
+how to set it up:
+
+```python no-style
+@require_torch_gpu
+@slow
+def test_example_slow_on_gpu():
+```
+
+Some decorators like `@parametrized` rewrite test names, therefore `@require_*` skip decorators have to be listed
+last for them to work correctly. Here is an example of the correct usage:
+
+```python no-style
+@parameterized.expand(...)
+@require_torch_multi_gpu
+def test_integration_foo():
+```
+
+This order problem doesn't exist with `@pytest.mark.parametrize`, you can put it first or last and it will still
+work. But it only works with non-unittests.
+
+Inside tests:
+
+- How many GPUs are available:
+
+```python
+from transformers.testing_utils import get_gpu_count
+
+n_gpu = get_gpu_count() # works with torch and tf
+```
+
+### Testing with a specific PyTorch backend or device
+
+To run the test suite on a specific torch device add `TRANSFORMERS_TEST_DEVICE="$device"` where `$device` is the target backend. For example, to test on CPU only:
+
+```bash
+TRANSFORMERS_TEST_DEVICE="cpu" pytest tests/utils/test_logging.py
+```
+
+This variable is useful for testing custom or less common PyTorch backends such as `mps`, `xpu` or `npu`. It can also be used to achieve the same effect as `CUDA_VISIBLE_DEVICES` by targeting specific GPUs or testing in CPU-only mode.
+
+Certain devices will require an additional import after importing `torch` for the first time. This can be specified using the environment variable `TRANSFORMERS_TEST_BACKEND`:
+
+```bash
+TRANSFORMERS_TEST_BACKEND="torch_npu" pytest tests/utils/test_logging.py
+```
+Alternative backends may also require the replacement of device-specific functions. For example `torch.cuda.manual_seed` may need to be replaced with a device-specific seed setter like `torch.npu.manual_seed` or `torch.xpu.manual_seed` to correctly set a random seed on the device. To specify a new backend with backend-specific device functions when running the test suite, create a Python device specification file `spec.py` in the format:
+
+```python
+import torch
+import torch_npu # for xpu, replace it with `import intel_extension_for_pytorch`
+# !! Further additional imports can be added here !!
+
+# Specify the device name (eg. 'cuda', 'cpu', 'npu', 'xpu', 'mps')
+DEVICE_NAME = 'npu'
+
+# Specify device-specific backends to dispatch to.
+# If not specified, will fallback to 'default' in 'testing_utils.py`
+MANUAL_SEED_FN = torch.npu.manual_seed
+EMPTY_CACHE_FN = torch.npu.empty_cache
+DEVICE_COUNT_FN = torch.npu.device_count
+```
+This format also allows for specification of any additional imports required. To use this file to replace equivalent methods in the test suite, set the environment variable `TRANSFORMERS_TEST_DEVICE_SPEC` to the path of the spec file, e.g. `TRANSFORMERS_TEST_DEVICE_SPEC=spec.py`.
+
+Currently, only `MANUAL_SEED_FN`, `EMPTY_CACHE_FN` and `DEVICE_COUNT_FN` are supported for device-specific dispatch.
+
+### Distributed training
+
+`pytest` can't deal with distributed training directly. If this is attempted - the sub-processes don't do the right
+thing and end up thinking they are `pytest` and start running the test suite in loops. It works, however, if one
+spawns a normal process that then spawns off multiple workers and manages the IO pipes.
+
+Here are some tests that use it:
+
+- [test_trainer_distributed.py](https://github.com/huggingface/transformers/tree/main/tests/trainer/test_trainer_distributed.py)
+- [test_deepspeed.py](https://github.com/huggingface/transformers/tree/main/tests/deepspeed/test_deepspeed.py)
+
+To jump right into the execution point, search for the `execute_subprocess_async` call in those tests.
+
+You will need at least 2 GPUs to see these tests in action:
+
+```bash
+CUDA_VISIBLE_DEVICES=0,1 RUN_SLOW=1 pytest -sv tests/test_trainer_distributed.py
+```
+
+### Output capture
+
+During test execution any output sent to `stdout` and `stderr` is captured. If a test or a setup method fails, its
+according captured output will usually be shown along with the failure traceback.
+
+To disable output capturing and to get the `stdout` and `stderr` normally, use `-s` or `--capture=no`:
+
+```bash
+pytest -s tests/utils/test_logging.py
+```
+
+To send test results to JUnit format output:
+
+```bash
+pytest tests --junitxml=result.xml
+```
+
+### Color control
+
+To have no color (e.g., yellow on white background is not readable):
+
+```bash
+pytest --color=no tests/utils/test_logging.py
+```
+
+### Sending test report to online pastebin service
+
+Creating a URL for each test failure:
+
+```bash
+pytest --pastebin=failed tests/utils/test_logging.py
+```
+
+This will submit test run information to a remote Paste service and provide a URL for each failure. You may select
+tests as usual or add for example -x if you only want to send one particular failure.
+
+Creating a URL for a whole test session log:
+
+```bash
+pytest --pastebin=all tests/utils/test_logging.py
+```
+
+## Writing tests
+
+🤗 transformers tests are based on `unittest`, but run by `pytest`, so most of the time features from both systems
+can be used.
+
+You can read [here](https://docs.pytest.org/en/stable/unittest.html) which features are supported, but the important
+thing to remember is that most `pytest` fixtures don't work. Neither parametrization, but we use the module
+`parameterized` that works in a similar way.
+
+
+### Parametrization
+
+Often, there is a need to run the same test multiple times, but with different arguments. It could be done from within
+the test, but then there is no way of running that test for just one set of arguments.
+
+```python
+# test_this1.py
+import unittest
+from parameterized import parameterized
+
+
+class TestMathUnitTest(unittest.TestCase):
+ @parameterized.expand(
+ [
+ ("negative", -1.5, -2.0),
+ ("integer", 1, 1.0),
+ ("large fraction", 1.6, 1),
+ ]
+ )
+ def test_floor(self, name, input, expected):
+ assert_equal(math.floor(input), expected)
+```
+
+Now, by default this test will be run 3 times, each time with the last 3 arguments of `test_floor` being assigned the
+corresponding arguments in the parameter list.
+
+and you could run just the `negative` and `integer` sets of params with:
+
+```bash
+pytest -k "negative and integer" tests/test_mytest.py
+```
+
+or all but `negative` sub-tests, with:
+
+```bash
+pytest -k "not negative" tests/test_mytest.py
+```
+
+Besides using the `-k` filter that was just mentioned, you can find out the exact name of each sub-test and run any
+or all of them using their exact names.
+
+```bash
+pytest test_this1.py --collect-only -q
+```
+
+and it will list:
+
+```bash
+test_this1.py::TestMathUnitTest::test_floor_0_negative
+test_this1.py::TestMathUnitTest::test_floor_1_integer
+test_this1.py::TestMathUnitTest::test_floor_2_large_fraction
+```
+
+So now you can run just 2 specific sub-tests:
+
+```bash
+pytest test_this1.py::TestMathUnitTest::test_floor_0_negative test_this1.py::TestMathUnitTest::test_floor_1_integer
+```
+
+The module [parameterized](https://pypi.org/project/parameterized/) which is already in the developer dependencies
+of `transformers` works for both: `unittests` and `pytest` tests.
+
+If, however, the test is not a `unittest`, you may use `pytest.mark.parametrize` (or you may see it being used in
+some existing tests, mostly under `examples`).
+
+Here is the same example, this time using `pytest`'s `parametrize` marker:
+
+```python
+# test_this2.py
+import pytest
+
+
+@pytest.mark.parametrize(
+ "name, input, expected",
+ [
+ ("negative", -1.5, -2.0),
+ ("integer", 1, 1.0),
+ ("large fraction", 1.6, 1),
+ ],
+)
+def test_floor(name, input, expected):
+ assert_equal(math.floor(input), expected)
+```
+
+Same as with `parameterized`, with `pytest.mark.parametrize` you can have a fine control over which sub-tests are
+run, if the `-k` filter doesn't do the job. Except, this parametrization function creates a slightly different set of
+names for the sub-tests. Here is what they look like:
+
+```bash
+pytest test_this2.py --collect-only -q
+```
+
+and it will list:
+
+```bash
+test_this2.py::test_floor[integer-1-1.0]
+test_this2.py::test_floor[negative--1.5--2.0]
+test_this2.py::test_floor[large fraction-1.6-1]
+```
+
+So now you can run just the specific test:
+
+```bash
+pytest test_this2.py::test_floor[negative--1.5--2.0] test_this2.py::test_floor[integer-1-1.0]
+```
+
+as in the previous example.
+
+
+
+### Files and directories
+
+In tests often we need to know where things are relative to the current test file, and it's not trivial since the test
+could be invoked from more than one directory or could reside in sub-directories with different depths. A helper class
+`transformers.test_utils.TestCasePlus` solves this problem by sorting out all the basic paths and provides easy
+accessors to them:
+
+- `pathlib` objects (all fully resolved):
+
+ - `test_file_path` - the current test file path, i.e. `__file__`
+ - `test_file_dir` - the directory containing the current test file
+ - `tests_dir` - the directory of the `tests` test suite
+ - `examples_dir` - the directory of the `examples` test suite
+ - `repo_root_dir` - the directory of the repository
+ - `src_dir` - the directory of `src` (i.e. where the `transformers` sub-dir resides)
+
+- stringified paths---same as above but these return paths as strings, rather than `pathlib` objects:
+
+ - `test_file_path_str`
+ - `test_file_dir_str`
+ - `tests_dir_str`
+ - `examples_dir_str`
+ - `repo_root_dir_str`
+ - `src_dir_str`
+
+To start using those all you need is to make sure that the test resides in a subclass of
+`transformers.test_utils.TestCasePlus`. For example:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class PathExampleTest(TestCasePlus):
+ def test_something_involving_local_locations(self):
+ data_dir = self.tests_dir / "fixtures/tests_samples/wmt_en_ro"
+```
+
+If you don't need to manipulate paths via `pathlib` or you just need a path as a string, you can always invoked
+`str()` on the `pathlib` object or use the accessors ending with `_str`. For example:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class PathExampleTest(TestCasePlus):
+ def test_something_involving_stringified_locations(self):
+ examples_dir = self.examples_dir_str
+```
+
+### Temporary files and directories
+
+Using unique temporary files and directories are essential for parallel test running, so that the tests won't overwrite
+each other's data. Also we want to get the temporary files and directories removed at the end of each test that created
+them. Therefore, using packages like `tempfile`, which address these needs is essential.
+
+However, when debugging tests, you need to be able to see what goes into the temporary file or directory and you want
+to know it's exact path and not having it randomized on every test re-run.
+
+A helper class `transformers.test_utils.TestCasePlus` is best used for such purposes. It's a sub-class of
+`unittest.TestCase`, so we can easily inherit from it in the test modules.
+
+Here is an example of its usage:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class ExamplesTests(TestCasePlus):
+ def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+```
+
+This code creates a unique temporary directory, and sets `tmp_dir` to its location.
+
+- Create a unique temporary dir:
+
+```python
+def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+```
+
+`tmp_dir` will contain the path to the created temporary dir. It will be automatically removed at the end of the
+test.
+
+- Create a temporary dir of my choice, ensure it's empty before the test starts and don't empty it after the test.
+
+```python
+def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir("./xxx")
+```
+
+This is useful for debug when you want to monitor a specific directory and want to make sure the previous tests didn't
+leave any data in there.
+
+- You can override the default behavior by directly overriding the `before` and `after` args, leading to one of the
+ following behaviors:
+
+ - `before=True`: the temporary dir will always be cleared at the beginning of the test.
+ - `before=False`: if the temporary dir already existed, any existing files will remain there.
+ - `after=True`: the temporary dir will always be deleted at the end of the test.
+ - `after=False`: the temporary dir will always be left intact at the end of the test.
+
+
+
+In order to run the equivalent of `rm -r` safely, only subdirs of the project repository checkout are allowed if
+an explicit `tmp_dir` is used, so that by mistake no `/tmp` or similar important part of the filesystem will
+get nuked. i.e. please always pass paths that start with `./`.
+
+
+
+
+
+Each test can register multiple temporary directories and they all will get auto-removed, unless requested
+otherwise.
+
+
+
+### Temporary sys.path override
+
+If you need to temporary override `sys.path` to import from another test for example, you can use the
+`ExtendSysPath` context manager. Example:
+
+
+```python
+import os
+from transformers.testing_utils import ExtendSysPath
+
+bindir = os.path.abspath(os.path.dirname(__file__))
+with ExtendSysPath(f"{bindir}/.."):
+ from test_trainer import TrainerIntegrationCommon # noqa
+```
+
+### Skipping tests
+
+This is useful when a bug is found and a new test is written, yet the bug is not fixed yet. In order to be able to
+commit it to the main repository we need make sure it's skipped during `make test`.
+
+Methods:
+
+- A **skip** means that you expect your test to pass only if some conditions are met, otherwise pytest should skip
+ running the test altogether. Common examples are skipping windows-only tests on non-windows platforms, or skipping
+ tests that depend on an external resource which is not available at the moment (for example a database).
+
+- A **xfail** means that you expect a test to fail for some reason. A common example is a test for a feature not yet
+ implemented, or a bug not yet fixed. When a test passes despite being expected to fail (marked with
+ pytest.mark.xfail), it’s an xpass and will be reported in the test summary.
+
+One of the important differences between the two is that `skip` doesn't run the test, and `xfail` does. So if the
+code that's buggy causes some bad state that will affect other tests, do not use `xfail`.
+
+#### Implementation
+
+- Here is how to skip whole test unconditionally:
+
+```python no-style
+@unittest.skip(reason="this bug needs to be fixed")
+def test_feature_x():
+```
+
+or via pytest:
+
+```python no-style
+@pytest.mark.skip(reason="this bug needs to be fixed")
+```
+
+or the `xfail` way:
+
+```python no-style
+@pytest.mark.xfail
+def test_feature_x():
+```
+
+
+Here's how to skip a test based on internal checks within the test:
+
+```python
+def test_feature_x():
+ if not has_something():
+ pytest.skip("unsupported configuration")
+```
+
+or the whole module:
+
+```python
+import pytest
+
+if not pytest.config.getoption("--custom-flag"):
+ pytest.skip("--custom-flag is missing, skipping tests", allow_module_level=True)
+```
+
+or the `xfail` way:
+
+```python
+def test_feature_x():
+ pytest.xfail("expected to fail until bug XYZ is fixed")
+```
+
+- Here is how to skip all tests in a module if some import is missing:
+
+```python
+docutils = pytest.importorskip("docutils", minversion="0.3")
+```
+
+- Skip a test based on a condition:
+
+```python no-style
+@pytest.mark.skipif(sys.version_info < (3,6), reason="requires python3.6 or higher")
+def test_feature_x():
+```
+
+or:
+
+```python no-style
+@unittest.skipIf(torch_device == "cpu", "Can't do half precision")
+def test_feature_x():
+```
+
+or skip the whole module:
+
+```python no-style
+@pytest.mark.skipif(sys.platform == 'win32', reason="does not run on windows")
+class TestClass():
+ def test_feature_x(self):
+```
+
+More details, example and ways are [here](https://docs.pytest.org/en/latest/skipping.html).
+
+### Slow tests
+
+The library of tests is ever-growing, and some of the tests take minutes to run, therefore we can't afford waiting for
+an hour for the test suite to complete on CI. Therefore, with some exceptions for essential tests, slow tests should be
+marked as in the example below:
+
+```python no-style
+from transformers.testing_utils import slow
+@slow
+def test_integration_foo():
+```
+
+Once a test is marked as `@slow`, to run such tests set `RUN_SLOW=1` env var, e.g.:
+
+```bash
+RUN_SLOW=1 pytest tests
+```
+
+Some decorators like `@parameterized` rewrite test names, therefore `@slow` and the rest of the skip decorators
+`@require_*` have to be listed last for them to work correctly. Here is an example of the correct usage:
+
+```python no-style
+@parameterized.expand(...)
+@slow
+def test_integration_foo():
+```
+
+As explained at the beginning of this document, slow tests get to run on a scheduled basis, rather than in PRs CI
+checks. So it's possible that some problems will be missed during a PR submission and get merged. Such problems will
+get caught during the next scheduled CI job. But it also means that it's important to run the slow tests on your
+machine before submitting the PR.
+
+Here is a rough decision making mechanism for choosing which tests should be marked as slow:
+
+If the test is focused on one of the library's internal components (e.g., modeling files, tokenization files,
+pipelines), then we should run that test in the non-slow test suite. If it's focused on an other aspect of the library,
+such as the documentation or the examples, then we should run these tests in the slow test suite. And then, to refine
+this approach we should have exceptions:
+
+- All tests that need to download a heavy set of weights or a dataset that is larger than ~50MB (e.g., model or
+ tokenizer integration tests, pipeline integration tests) should be set to slow. If you're adding a new model, you
+ should create and upload to the hub a tiny version of it (with random weights) for integration tests. This is
+ discussed in the following paragraphs.
+- All tests that need to do a training not specifically optimized to be fast should be set to slow.
+- We can introduce exceptions if some of these should-be-non-slow tests are excruciatingly slow, and set them to
+ `@slow`. Auto-modeling tests, which save and load large files to disk, are a good example of tests that are marked
+ as `@slow`.
+- If a test completes under 1 second on CI (including downloads if any) then it should be a normal test regardless.
+
+Collectively, all the non-slow tests need to cover entirely the different internals, while remaining fast. For example,
+a significant coverage can be achieved by testing with specially created tiny models with random weights. Such models
+have the very minimal number of layers (e.g., 2), vocab size (e.g., 1000), etc. Then the `@slow` tests can use large
+slow models to do qualitative testing. To see the use of these simply look for *tiny* models with:
+
+```bash
+grep tiny tests examples
+```
+
+Here is an example of a [script](https://github.com/huggingface/transformers/tree/main/scripts/fsmt/fsmt-make-tiny-model.py) that created the tiny model
+[stas/tiny-wmt19-en-de](https://huggingface.co/stas/tiny-wmt19-en-de). You can easily adjust it to your specific
+model's architecture.
+
+It's easy to measure the run-time incorrectly if for example there is an overheard of downloading a huge model, but if
+you test it locally the downloaded files would be cached and thus the download time not measured. Hence check the
+execution speed report in CI logs instead (the output of `pytest --durations=0 tests`).
+
+That report is also useful to find slow outliers that aren't marked as such, or which need to be re-written to be fast.
+If you notice that the test suite starts getting slow on CI, the top listing of this report will show the slowest
+tests.
+
+
+### Testing the stdout/stderr output
+
+In order to test functions that write to `stdout` and/or `stderr`, the test can access those streams using the
+`pytest`'s [capsys system](https://docs.pytest.org/en/latest/capture.html). Here is how this is accomplished:
+
+```python
+import sys
+
+
+def print_to_stdout(s):
+ print(s)
+
+
+def print_to_stderr(s):
+ sys.stderr.write(s)
+
+
+def test_result_and_stdout(capsys):
+ msg = "Hello"
+ print_to_stdout(msg)
+ print_to_stderr(msg)
+ out, err = capsys.readouterr() # consume the captured output streams
+ # optional: if you want to replay the consumed streams:
+ sys.stdout.write(out)
+ sys.stderr.write(err)
+ # test:
+ assert msg in out
+ assert msg in err
+```
+
+And, of course, most of the time, `stderr` will come as a part of an exception, so try/except has to be used in such
+a case:
+
+```python
+def raise_exception(msg):
+ raise ValueError(msg)
+
+
+def test_something_exception():
+ msg = "Not a good value"
+ error = ""
+ try:
+ raise_exception(msg)
+ except Exception as e:
+ error = str(e)
+ assert msg in error, f"{msg} is in the exception:\n{error}"
+```
+
+Another approach to capturing stdout is via `contextlib.redirect_stdout`:
+
+```python
+from io import StringIO
+from contextlib import redirect_stdout
+
+
+def print_to_stdout(s):
+ print(s)
+
+
+def test_result_and_stdout():
+ msg = "Hello"
+ buffer = StringIO()
+ with redirect_stdout(buffer):
+ print_to_stdout(msg)
+ out = buffer.getvalue()
+ # optional: if you want to replay the consumed streams:
+ sys.stdout.write(out)
+ # test:
+ assert msg in out
+```
+
+An important potential issue with capturing stdout is that it may contain `\r` characters that in normal `print`
+reset everything that has been printed so far. There is no problem with `pytest`, but with `pytest -s` these
+characters get included in the buffer, so to be able to have the test run with and without `-s`, you have to make an
+extra cleanup to the captured output, using `re.sub(r'~.*\r', '', buf, 0, re.M)`.
+
+But, then we have a helper context manager wrapper to automatically take care of it all, regardless of whether it has
+some `\r`'s in it or not, so it's a simple:
+
+```python
+from transformers.testing_utils import CaptureStdout
+
+with CaptureStdout() as cs:
+ function_that_writes_to_stdout()
+print(cs.out)
+```
+
+Here is a full test example:
+
+```python
+from transformers.testing_utils import CaptureStdout
+
+msg = "Secret message\r"
+final = "Hello World"
+with CaptureStdout() as cs:
+ print(msg + final)
+assert cs.out == final + "\n", f"captured: {cs.out}, expecting {final}"
+```
+
+If you'd like to capture `stderr` use the `CaptureStderr` class instead:
+
+```python
+from transformers.testing_utils import CaptureStderr
+
+with CaptureStderr() as cs:
+ function_that_writes_to_stderr()
+print(cs.err)
+```
+
+If you need to capture both streams at once, use the parent `CaptureStd` class:
+
+```python
+from transformers.testing_utils import CaptureStd
+
+with CaptureStd() as cs:
+ function_that_writes_to_stdout_and_stderr()
+print(cs.err, cs.out)
+```
+
+Also, to aid debugging test issues, by default these context managers automatically replay the captured streams on exit
+from the context.
+
+
+### Capturing logger stream
+
+If you need to validate the output of a logger, you can use `CaptureLogger`:
+
+```python
+from transformers import logging
+from transformers.testing_utils import CaptureLogger
+
+msg = "Testing 1, 2, 3"
+logging.set_verbosity_info()
+logger = logging.get_logger("transformers.models.bart.tokenization_bart")
+with CaptureLogger(logger) as cl:
+ logger.info(msg)
+assert cl.out, msg + "\n"
+```
+
+### Testing with environment variables
+
+If you want to test the impact of environment variables for a specific test you can use a helper decorator
+`transformers.testing_utils.mockenv`
+
+```python
+from transformers.testing_utils import mockenv
+
+
+class HfArgumentParserTest(unittest.TestCase):
+ @mockenv(TRANSFORMERS_VERBOSITY="error")
+ def test_env_override(self):
+ env_level_str = os.getenv("TRANSFORMERS_VERBOSITY", None)
+```
+
+At times an external program needs to be called, which requires setting `PYTHONPATH` in `os.environ` to include
+multiple local paths. A helper class `transformers.test_utils.TestCasePlus` comes to help:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class EnvExampleTest(TestCasePlus):
+ def test_external_prog(self):
+ env = self.get_env()
+ # now call the external program, passing `env` to it
+```
+
+Depending on whether the test file was under the `tests` test suite or `examples` it'll correctly set up
+`env[PYTHONPATH]` to include one of these two directories, and also the `src` directory to ensure the testing is
+done against the current repo, and finally with whatever `env[PYTHONPATH]` was already set to before the test was
+called if anything.
+
+This helper method creates a copy of the `os.environ` object, so the original remains intact.
+
+
+### Getting reproducible results
+
+In some situations you may want to remove randomness for your tests. To get identical reproducible results set, you
+will need to fix the seed:
+
+```python
+seed = 42
+
+# python RNG
+import random
+
+random.seed(seed)
+
+# pytorch RNGs
+import torch
+
+torch.manual_seed(seed)
+torch.backends.cudnn.deterministic = True
+if torch.cuda.is_available():
+ torch.cuda.manual_seed_all(seed)
+
+# numpy RNG
+import numpy as np
+
+np.random.seed(seed)
+
+# tf RNG
+import tensorflow as tf
+
+tf.random.set_seed(seed)
+```
+
+### Debugging tests
+
+To start a debugger at the point of the warning, do this:
+
+```bash
+pytest tests/utils/test_logging.py -W error::UserWarning --pdb
+```
+
+## Working with github actions workflows
+
+To trigger a self-push workflow CI job, you must:
+
+1. Create a new branch on `transformers` origin (not a fork!).
+2. The branch name has to start with either `ci_` or `ci-` (`main` triggers it too, but we can't do PRs on
+ `main`). It also gets triggered only for specific paths - you can find the up-to-date definition in case it
+ changed since this document has been written [here](https://github.com/huggingface/transformers/blob/main/.github/workflows/self-push.yml) under *push:*
+3. Create a PR from this branch.
+4. Then you can see the job appear [here](https://github.com/huggingface/transformers/actions/workflows/self-push.yml). It may not run right away if there
+ is a backlog.
+
+
+
+
+## Testing Experimental CI Features
+
+Testing CI features can be potentially problematic as it can interfere with the normal CI functioning. Therefore if a
+new CI feature is to be added, it should be done as following.
+
+1. Create a new dedicated job that tests what needs to be tested
+2. The new job must always succeed so that it gives us a green ✓ (details below).
+3. Let it run for some days to see that a variety of different PR types get to run on it (user fork branches,
+ non-forked branches, branches originating from github.com UI direct file edit, various forced pushes, etc. - there
+ are so many) while monitoring the experimental job's logs (not the overall job green as it's purposefully always
+ green)
+4. When it's clear that everything is solid, then merge the new changes into existing jobs.
+
+That way experiments on CI functionality itself won't interfere with the normal workflow.
+
+Now how can we make the job always succeed while the new CI feature is being developed?
+
+Some CIs, like TravisCI support ignore-step-failure and will report the overall job as successful, but CircleCI and
+Github Actions as of this writing don't support that.
+
+So the following workaround can be used:
+
+1. `set +euo pipefail` at the beginning of the run command to suppress most potential failures in the bash script.
+2. the last command must be a success: `echo "done"` or just `true` will do
+
+Here is an example:
+
+```yaml
+- run:
+ name: run CI experiment
+ command: |
+ set +euo pipefail
+ echo "setting run-all-despite-any-errors-mode"
+ this_command_will_fail
+ echo "but bash continues to run"
+ # emulate another failure
+ false
+ # but the last command must be a success
+ echo "during experiment do not remove: reporting success to CI, even if there were failures"
+```
+
+For simple commands you could also do:
+
+```bash
+cmd_that_may_fail || true
+```
+
+Of course, once satisfied with the results, integrate the experimental step or job with the rest of the normal jobs,
+while removing `set +euo pipefail` or any other things you may have added to ensure that the experimental job doesn't
+interfere with the normal CI functioning.
+
+This whole process would have been much easier if we only could set something like `allow-failure` for the
+experimental step, and let it fail without impacting the overall status of PRs. But as mentioned earlier CircleCI and
+Github Actions don't support it at the moment.
+
+You can vote for this feature and see where it is at these CI-specific threads:
+
+- [Github Actions:](https://github.com/actions/toolkit/issues/399)
+- [CircleCI:](https://ideas.circleci.com/ideas/CCI-I-344)
+
+## DeepSpeed integration
+
+For a PR that involves the DeepSpeed integration, keep in mind our CircleCI PR CI setup doesn't have GPUs. Tests requiring GPUs are run on a different CI nightly. This means if you get a passing CI report in your PR, it doesn’t mean the DeepSpeed tests pass.
+
+To run DeepSpeed tests:
+
+```bash
+RUN_SLOW=1 pytest tests/deepspeed/test_deepspeed.py
+```
+
+Any changes to the modeling or PyTorch examples code requires running the model zoo tests as well.
+
+```bash
+RUN_SLOW=1 pytest tests/deepspeed
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tf_xla.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tf_xla.md
new file mode 100644
index 0000000000000000000000000000000000000000..a585aec068b1f380f23428d401ceeb958970e2a6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tf_xla.md
@@ -0,0 +1,174 @@
+
+
+# XLA Integration for TensorFlow Models
+
+[[open-in-colab]]
+
+Accelerated Linear Algebra, dubbed XLA, is a compiler for accelerating the runtime of TensorFlow Models. From the [official documentation](https://www.tensorflow.org/xla):
+
+XLA (Accelerated Linear Algebra) is a domain-specific compiler for linear algebra that can accelerate TensorFlow models with potentially no source code changes.
+
+Using XLA in TensorFlow is simple – it comes packaged inside the `tensorflow` library, and it can be triggered with the `jit_compile` argument in any graph-creating function such as [`tf.function`](https://www.tensorflow.org/guide/intro_to_graphs). When using Keras methods like `fit()` and `predict()`, you can enable XLA simply by passing the `jit_compile` argument to `model.compile()`. However, XLA is not limited to these methods - it can also be used to accelerate any arbitrary `tf.function`.
+
+Several TensorFlow methods in 🤗 Transformers have been rewritten to be XLA-compatible, including text generation for models such as [GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2), [T5](https://huggingface.co/docs/transformers/model_doc/t5) and [OPT](https://huggingface.co/docs/transformers/model_doc/opt), as well as speech processing for models such as [Whisper](https://huggingface.co/docs/transformers/model_doc/whisper).
+
+While the exact amount of speed-up is very much model-dependent, for TensorFlow text generation models inside 🤗 Transformers, we noticed a speed-up of ~100x. This document will explain how you can use XLA for these models to get the maximum amount of performance. We’ll also provide links to additional resources if you’re interested to learn more about the benchmarks and our design philosophy behind the XLA integration.
+
+## Running TF functions with XLA
+
+Let us consider the following model in TensorFlow:
+
+```py
+import tensorflow as tf
+
+model = tf.keras.Sequential(
+ [tf.keras.layers.Dense(10, input_shape=(10,), activation="relu"), tf.keras.layers.Dense(5, activation="softmax")]
+)
+```
+
+The above model accepts inputs having a dimension of `(10, )`. We can use the model for running a forward pass like so:
+
+```py
+# Generate random inputs for the model.
+batch_size = 16
+input_vector_dim = 10
+random_inputs = tf.random.normal((batch_size, input_vector_dim))
+
+# Run a forward pass.
+_ = model(random_inputs)
+```
+
+In order to run the forward pass with an XLA-compiled function, we’d need to do:
+
+```py
+xla_fn = tf.function(model, jit_compile=True)
+_ = xla_fn(random_inputs)
+```
+
+The default `call()` function of the `model` is used for compiling the XLA graph. But if there’s any other model function you want to compile into XLA that’s also possible with:
+
+```py
+my_xla_fn = tf.function(model.my_xla_fn, jit_compile=True)
+```
+
+## Running a TF text generation model with XLA from 🤗 Transformers
+
+To enable XLA-accelerated generation within 🤗 Transformers, you need to have a recent version of `transformers` installed. You can install it by running:
+
+```bash
+pip install transformers --upgrade
+```
+
+And then you can run the following code:
+
+```py
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+# Will error if the minimal version of Transformers is not installed.
+from transformers.utils import check_min_version
+
+check_min_version("4.21.0")
+
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+input_string = ["TensorFlow is"]
+
+# One line to create an XLA generation function
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+tokenized_input = tokenizer(input_string, return_tensors="tf")
+generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+
+decoded_text = tokenizer.decode(generated_tokens[0], skip_special_tokens=True)
+print(f"Generated -- {decoded_text}")
+# Generated -- TensorFlow is an open-source, open-source, distributed-source application # framework for the
+```
+
+As you can notice, enabling XLA on `generate()` is just a single line of code. The rest of the code remains unchanged. However, there are a couple of gotchas in the above code snippet that are specific to XLA. You need to be aware of those to realize the speed-ups that XLA can bring in. We discuss these in the following section.
+
+## Gotchas to be aware of
+
+When you are executing an XLA-enabled function (like `xla_generate()` above) for the first time, it will internally try to infer the computation graph, which is time-consuming. This process is known as [“tracing”](https://www.tensorflow.org/guide/intro_to_graphs#when_is_a_function_tracing).
+
+You might notice that the generation time is not fast. Successive calls of `xla_generate()` (or any other XLA-enabled function) won’t have to infer the computation graph, given the inputs to the function follow the same shape with which the computation graph was initially built. While this is not a problem for modalities with fixed input shapes (e.g., images), you must pay attention if you are working with variable input shape modalities (e.g., text).
+
+To ensure `xla_generate()` always operates with the same input shapes, you can specify the `padding` arguments when calling the tokenizer.
+
+```py
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+input_string = ["TensorFlow is"]
+
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+# Here, we call the tokenizer with padding options.
+tokenized_input = tokenizer(input_string, pad_to_multiple_of=8, padding=True, return_tensors="tf")
+
+generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+decoded_text = tokenizer.decode(generated_tokens[0], skip_special_tokens=True)
+print(f"Generated -- {decoded_text}")
+```
+
+This way, you can ensure that the inputs to `xla_generate()` will always receive inputs with the shape it was traced with and thus leading to speed-ups in the generation time. You can verify this with the code below:
+
+```py
+import time
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+for input_string in ["TensorFlow is", "TensorFlow is a", "TFLite is a"]:
+ tokenized_input = tokenizer(input_string, pad_to_multiple_of=8, padding=True, return_tensors="tf")
+ start = time.time_ns()
+ generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+ end = time.time_ns()
+ print(f"Execution time -- {(end - start) / 1e6:.1f} ms\n")
+```
+
+On a Tesla T4 GPU, you can expect the outputs like so:
+
+```bash
+Execution time -- 30819.6 ms
+
+Execution time -- 79.0 ms
+
+Execution time -- 78.9 ms
+```
+The first call to `xla_generate()` is time-consuming because of tracing, but the successive calls are orders of magnitude faster. Keep in mind that any change in the generation options at any point will trigger re-tracing and thus leading to slow-downs in the generation time.
+
+We didn’t cover all the text generation options 🤗 Transformers provides in this document. We encourage you to read the documentation for advanced use cases.
+
+## Additional Resources
+
+Here, we leave you with some additional resources if you want to delve deeper into XLA in 🤗 Transformers and in general.
+
+* [This Colab Notebook](https://colab.research.google.com/github/huggingface/blog/blob/main/notebooks/91_tf_xla_generate.ipynb) provides an interactive demonstration if you want to fiddle with the XLA-compatible encoder-decoder (like [T5](https://huggingface.co/docs/transformers/model_doc/t5)) and decoder-only (like [GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2)) text generation models.
+* [This blog post](https://huggingface.co/blog/tf-xla-generate) provides an overview of the comparison benchmarks for XLA-compatible models along with a friendly introduction to XLA in TensorFlow.
+* [This blog post](https://blog.tensorflow.org/2022/11/how-hugging-face-improved-text-generation-performance-with-xla.html) discusses our design philosophy behind adding XLA support to the TensorFlow models in 🤗 Transformers.
+* Recommended posts for learning more about XLA and TensorFlow graphs in general:
+ * [XLA: Optimizing Compiler for Machine Learning](https://www.tensorflow.org/xla)
+ * [Introduction to graphs and tf.function](https://www.tensorflow.org/guide/intro_to_graphs)
+ * [Better performance with tf.function](https://www.tensorflow.org/guide/function)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tflite.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tflite.md
new file mode 100644
index 0000000000000000000000000000000000000000..09434a81508d35e795b95b8704110df2039aac97
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tflite.md
@@ -0,0 +1,62 @@
+
+
+# Export to TFLite
+
+[TensorFlow Lite](https://www.tensorflow.org/lite/guide) is a lightweight framework for deploying machine learning models
+on resource-constrained devices, such as mobile phones, embedded systems, and Internet of Things (IoT) devices.
+TFLite is designed to optimize and run models efficiently on these devices with limited computational power, memory, and
+power consumption.
+A TensorFlow Lite model is represented in a special efficient portable format identified by the `.tflite` file extension.
+
+🤗 Optimum offers functionality to export 🤗 Transformers models to TFLite through the `exporters.tflite` module.
+For the list of supported model architectures, please refer to [🤗 Optimum documentation](https://huggingface.co/docs/optimum/exporters/tflite/overview).
+
+To export a model to TFLite, install the required dependencies:
+
+```bash
+pip install optimum[exporters-tf]
+```
+
+To check out all available arguments, refer to the [🤗 Optimum docs](https://huggingface.co/docs/optimum/main/en/exporters/tflite/usage_guides/export_a_model),
+or view help in command line:
+
+```bash
+optimum-cli export tflite --help
+```
+
+To export a model's checkpoint from the 🤗 Hub, for example, `google-bert/bert-base-uncased`, run the following command:
+
+```bash
+optimum-cli export tflite --model google-bert/bert-base-uncased --sequence_length 128 bert_tflite/
+```
+
+You should see the logs indicating progress and showing where the resulting `model.tflite` is saved, like this:
+
+```bash
+Validating TFLite model...
+ -[✓] TFLite model output names match reference model (logits)
+ - Validating TFLite Model output "logits":
+ -[✓] (1, 128, 30522) matches (1, 128, 30522)
+ -[x] values not close enough, max diff: 5.817413330078125e-05 (atol: 1e-05)
+The TensorFlow Lite export succeeded with the warning: The maximum absolute difference between the output of the reference model and the TFLite exported model is not within the set tolerance 1e-05:
+- logits: max diff = 5.817413330078125e-05.
+ The exported model was saved at: bert_tflite
+ ```
+
+The example above illustrates exporting a checkpoint from 🤗 Hub. When exporting a local model, first make sure that you
+saved both the model's weights and tokenizer files in the same directory (`local_path`). When using CLI, pass the
+`local_path` to the `model` argument instead of the checkpoint name on 🤗 Hub.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tiktoken.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tiktoken.md
new file mode 100644
index 0000000000000000000000000000000000000000..aac81e24fdd7387695c3add6d02ac6da840d4d13
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tiktoken.md
@@ -0,0 +1,60 @@
+
+
+# Tiktoken and interaction with Transformers
+
+Support for tiktoken model files is seamlessly integrated in 🤗 transformers when loading models
+`from_pretrained` with a `tokenizer.model` tiktoken file on the Hub, which is automatically converted into our
+[fast tokenizer](https://huggingface.co/docs/transformers/main/en/main_classes/tokenizer#transformers.PreTrainedTokenizerFast).
+
+### Known models that were released with a `tiktoken.model`:
+ - gpt2
+ - llama3
+
+## Example usage
+
+In order to load `tiktoken` files in `transformers`, ensure that the `tokenizer.model` file is a tiktoken file and it
+will automatically be loaded when loading `from_pretrained`. Here is how one would load a tokenizer and a model, which
+ can be loaded from the exact same file:
+
+```py
+from transformers import AutoTokenizer
+
+model_id = "meta-llama/Meta-Llama-3-8B-Instruct"
+tokenizer = AutoTokenizer.from_pretrained(model_id, subfolder="original")
+```
+## Create tiktoken tokenizer
+
+The `tokenizer.model` file contains no information about additional tokens or pattern strings. If these are important, convert the tokenizer to `tokenizer.json`, the appropriate format for [`PreTrainedTokenizerFast`].
+
+Generate the `tokenizer.model` file with [tiktoken.get_encoding](https://github.com/openai/tiktoken/blob/63527649963def8c759b0f91f2eb69a40934e468/tiktoken/registry.py#L63) and then convert it to `tokenizer.json` with [`convert_tiktoken_to_fast`].
+
+```py
+
+from transformers.integrations.tiktoken import convert_tiktoken_to_fast
+from tiktoken import get_encoding
+
+# You can load your custom encoding or the one provided by OpenAI
+encoding = get_encoding("gpt2")
+convert_tiktoken_to_fast(encoding, "config/save/dir")
+```
+
+The resulting `tokenizer.json` file is saved to the specified directory and can be loaded with [`PreTrainedTokenizerFast`].
+
+```py
+tokenizer = PreTrainedTokenizerFast.from_pretrained("config/save/dir")
+```
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tokenizer_summary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tokenizer_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..c5f12dd20d20ed6750aa070d95e519690bf686a7
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/tokenizer_summary.md
@@ -0,0 +1,282 @@
+
+
+# Summary of the tokenizers
+
+[[open-in-colab]]
+
+On this page, we will have a closer look at tokenization.
+
+", "ug"]` since
+the symbol `"m"` is not in the base vocabulary. In general, single letters such as `"m"` are not replaced by the
+`""` symbol because the training data usually includes at least one occurrence of each letter, but it is likely
+to happen for very special characters like emojis.
+
+As mentioned earlier, the vocabulary size, *i.e.* the base vocabulary size + the number of merges, is a hyperparameter
+to choose. For instance [GPT](model_doc/openai-gpt) has a vocabulary size of 40,478 since they have 478 base characters
+and chose to stop training after 40,000 merges.
+
+#### Byte-level BPE
+
+A base vocabulary that includes all possible base characters can be quite large if *e.g.* all unicode characters are
+considered as base characters. To have a better base vocabulary, [GPT-2](https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf) uses bytes
+as the base vocabulary, which is a clever trick to force the base vocabulary to be of size 256 while ensuring that
+every base character is included in the vocabulary. With some additional rules to deal with punctuation, the GPT2's
+tokenizer can tokenize every text without the need for the symbol. [GPT-2](model_doc/gpt) has a vocabulary
+size of 50,257, which corresponds to the 256 bytes base tokens, a special end-of-text token and the symbols learned
+with 50,000 merges.
+
+
+
+This is the very beginning of our experiments with TorchScript and we are still
+exploring its capabilities with variable-input-size models. It is a focus of interest to
+us and we will deepen our analysis in upcoming releases, with more code examples, a more
+flexible implementation, and benchmarks comparing Python-based codes with compiled
+TorchScript.
+
+
+
+According to the [TorchScript documentation](https://pytorch.org/docs/stable/jit.html):
+
+> TorchScript is a way to create serializable and optimizable models from PyTorch code.
+
+There are two PyTorch modules, [JIT and
+TRACE](https://pytorch.org/docs/stable/jit.html), that allow developers to export their
+models to be reused in other programs like efficiency-oriented C++ programs.
+
+We provide an interface that allows you to export 🤗 Transformers models to TorchScript
+so they can be reused in a different environment than PyTorch-based Python programs.
+Here, we explain how to export and use our models using TorchScript.
+
+Exporting a model requires two things:
+
+- model instantiation with the `torchscript` flag
+- a forward pass with dummy inputs
+
+These necessities imply several things developers should be careful about as detailed
+below.
+
+## TorchScript flag and tied weights
+
+The `torchscript` flag is necessary because most of the 🤗 Transformers language models
+have tied weights between their `Embedding` layer and their `Decoding` layer.
+TorchScript does not allow you to export models that have tied weights, so it is
+necessary to untie and clone the weights beforehand.
+
+Models instantiated with the `torchscript` flag have their `Embedding` layer and
+`Decoding` layer separated, which means that they should not be trained down the line.
+Training would desynchronize the two layers, leading to unexpected results.
+
+This is not the case for models that do not have a language model head, as those do not
+have tied weights. These models can be safely exported without the `torchscript` flag.
+
+## Dummy inputs and standard lengths
+
+The dummy inputs are used for a models forward pass. While the inputs' values are
+propagated through the layers, PyTorch keeps track of the different operations executed
+on each tensor. These recorded operations are then used to create the *trace* of the
+model.
+
+The trace is created relative to the inputs' dimensions. It is therefore constrained by
+the dimensions of the dummy input, and will not work for any other sequence length or
+batch size. When trying with a different size, the following error is raised:
+
+```
+`The expanded size of the tensor (3) must match the existing size (7) at non-singleton dimension 2`
+```
+
+We recommended you trace the model with a dummy input size at least as large as the
+largest input that will be fed to the model during inference. Padding can help fill the
+missing values. However, since the model is traced with a larger input size, the
+dimensions of the matrix will also be large, resulting in more calculations.
+
+Be careful of the total number of operations done on each input and follow the
+performance closely when exporting varying sequence-length models.
+
+## Using TorchScript in Python
+
+This section demonstrates how to save and load models as well as how to use the trace
+for inference.
+
+### Saving a model
+
+To export a `BertModel` with TorchScript, instantiate `BertModel` from the `BertConfig`
+class and then save it to disk under the filename `traced_bert.pt`:
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+
+enc = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+
+# Tokenizing input text
+text = "[CLS] Who was Jim Henson ? [SEP] Jim Henson was a puppeteer [SEP]"
+tokenized_text = enc.tokenize(text)
+
+# Masking one of the input tokens
+masked_index = 8
+tokenized_text[masked_index] = "[MASK]"
+indexed_tokens = enc.convert_tokens_to_ids(tokenized_text)
+segments_ids = [0, 0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1]
+
+# Creating a dummy input
+tokens_tensor = torch.tensor([indexed_tokens])
+segments_tensors = torch.tensor([segments_ids])
+dummy_input = [tokens_tensor, segments_tensors]
+
+# Initializing the model with the torchscript flag
+# Flag set to True even though it is not necessary as this model does not have an LM Head.
+config = BertConfig(
+ vocab_size_or_config_json_file=32000,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ torchscript=True,
+)
+
+# Instantiating the model
+model = BertModel(config)
+
+# The model needs to be in evaluation mode
+model.eval()
+
+# If you are instantiating the model with *from_pretrained* you can also easily set the TorchScript flag
+model = BertModel.from_pretrained("google-bert/bert-base-uncased", torchscript=True)
+
+# Creating the trace
+traced_model = torch.jit.trace(model, [tokens_tensor, segments_tensors])
+torch.jit.save(traced_model, "traced_bert.pt")
+```
+
+### Loading a model
+
+Now you can load the previously saved `BertModel`, `traced_bert.pt`, from disk and use
+it on the previously initialised `dummy_input`:
+
+```python
+loaded_model = torch.jit.load("traced_bert.pt")
+loaded_model.eval()
+
+all_encoder_layers, pooled_output = loaded_model(*dummy_input)
+```
+
+### Using a traced model for inference
+
+Use the traced model for inference by using its `__call__` dunder method:
+
+```python
+traced_model(tokens_tensor, segments_tensors)
+```
+
+## Deploy Hugging Face TorchScript models to AWS with the Neuron SDK
+
+AWS introduced the [Amazon EC2 Inf1](https://aws.amazon.com/ec2/instance-types/inf1/)
+instance family for low cost, high performance machine learning inference in the cloud.
+The Inf1 instances are powered by the AWS Inferentia chip, a custom-built hardware
+accelerator, specializing in deep learning inferencing workloads. [AWS
+Neuron](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/#) is the SDK for
+Inferentia that supports tracing and optimizing transformers models for deployment on
+Inf1. The Neuron SDK provides:
+
+
+1. Easy-to-use API with one line of code change to trace and optimize a TorchScript
+ model for inference in the cloud.
+2. Out of the box performance optimizations for [improved
+ cost-performance](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/benchmark/>).
+3. Support for Hugging Face transformers models built with either
+ [PyTorch](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/bert_tutorial/tutorial_pretrained_bert.html)
+ or
+ [TensorFlow](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/tensorflow/huggingface_bert/huggingface_bert.html).
+
+### Implications
+
+Transformers models based on the [BERT (Bidirectional Encoder Representations from
+Transformers)](https://huggingface.co/docs/transformers/main/model_doc/bert)
+architecture, or its variants such as
+[distilBERT](https://huggingface.co/docs/transformers/main/model_doc/distilbert) and
+[roBERTa](https://huggingface.co/docs/transformers/main/model_doc/roberta) run best on
+Inf1 for non-generative tasks such as extractive question answering, sequence
+classification, and token classification. However, text generation tasks can still be
+adapted to run on Inf1 according to this [AWS Neuron MarianMT
+tutorial](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/transformers-marianmt.html).
+More information about models that can be converted out of the box on Inferentia can be
+found in the [Model Architecture
+Fit](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/models/models-inferentia.html#models-inferentia)
+section of the Neuron documentation.
+
+### Dependencies
+
+Using AWS Neuron to convert models requires a [Neuron SDK
+environment](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/neuron-frameworks/pytorch-neuron/index.html#installation-guide)
+which comes preconfigured on [AWS Deep Learning
+AMI](https://docs.aws.amazon.com/dlami/latest/devguide/tutorial-inferentia-launching.html).
+
+### Converting a model for AWS Neuron
+
+Convert a model for AWS NEURON using the same code from [Using TorchScript in
+Python](torchscript#using-torchscript-in-python) to trace a `BertModel`. Import the
+`torch.neuron` framework extension to access the components of the Neuron SDK through a
+Python API:
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+import torch.neuron
+```
+
+You only need to modify the following line:
+
+```diff
+- torch.jit.trace(model, [tokens_tensor, segments_tensors])
++ torch.neuron.trace(model, [tokens_tensor, segments_tensors])
+```
+
+This enables the Neuron SDK to trace the model and optimize it for Inf1 instances.
+
+To learn more about AWS Neuron SDK features, tools, example tutorials and latest
+updates, please see the [AWS NeuronSDK
+documentation](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/index.html).
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/trainer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/trainer.md
new file mode 100644
index 0000000000000000000000000000000000000000..e3a66f420424858b10f660bb3077d690e62a1984
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/trainer.md
@@ -0,0 +1,753 @@
+
+
+# Trainer
+
+The [`Trainer`] is a complete training and evaluation loop for PyTorch models implemented in the Transformers library. You only need to pass it the necessary pieces for training (model, tokenizer, dataset, evaluation function, training hyperparameters, etc.), and the [`Trainer`] class takes care of the rest. This makes it easier to start training faster without manually writing your own training loop. But at the same time, [`Trainer`] is very customizable and offers a ton of training options so you can tailor it to your exact training needs.
+
+
+
+In addition to the [`Trainer`] class, Transformers also provides a [`Seq2SeqTrainer`] class for sequence-to-sequence tasks like translation or summarization. There is also the [`~trl.SFTTrainer`] class from the [TRL](https://hf.co/docs/trl) library which wraps the [`Trainer`] class and is optimized for training language models like Llama-2 and Mistral with autoregressive techniques. [`~trl.SFTTrainer`] also supports features like sequence packing, LoRA, quantization, and DeepSpeed for efficiently scaling to any model size.
+
+
+
+Before you start, make sure [Accelerate](https://hf.co/docs/accelerate) - a library for enabling and running PyTorch training across distributed environments - is installed.
+
+```bash
+pip install accelerate
+
+# upgrade
+pip install accelerate --upgrade
+```
+
+This guide provides an overview of the [`Trainer`] class.
+
+## Basic usage
+
+[`Trainer`] includes all the code you'll find in a basic training loop:
+
+1. perform a training step to calculate the loss
+2. calculate the gradients with the [`~accelerate.Accelerator.backward`] method
+3. update the weights based on the gradients
+4. repeat this process until you've reached a predetermined number of epochs
+
+The [`Trainer`] class abstracts all of this code away so you don't have to worry about manually writing a training loop every time or if you're just getting started with PyTorch and training. You only need to provide the essential components required for training, such as a model and a dataset, and the [`Trainer`] class handles everything else.
+
+If you want to specify any training options or hyperparameters, you can find them in the [`TrainingArguments`] class. For example, let's define where to save the model in `output_dir` and push the model to the Hub after training with `push_to_hub=True`.
+
+```py
+from transformers import TrainingArguments
+
+training_args = TrainingArguments(
+ output_dir="your-model",
+ learning_rate=2e-5,
+ per_device_train_batch_size=16,
+ per_device_eval_batch_size=16,
+ num_train_epochs=2,
+ weight_decay=0.01,
+ eval_strategy="epoch",
+ save_strategy="epoch",
+ load_best_model_at_end=True,
+ push_to_hub=True,
+)
+```
+
+Pass `training_args` to the [`Trainer`] along with a model, dataset, something to preprocess the dataset with (depending on your data type it could be a tokenizer, feature extractor or image processor), a data collator, and a function to compute the metrics you want to track during training.
+
+Finally, call [`~Trainer.train`] to start training!
+
+```py
+from transformers import Trainer
+
+trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=dataset["train"],
+ eval_dataset=dataset["test"],
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics,
+)
+
+trainer.train()
+```
+
+### Checkpoints
+
+The [`Trainer`] class saves your model checkpoints to the directory specified in the `output_dir` parameter of [`TrainingArguments`]. You'll find the checkpoints saved in a `checkpoint-000` subfolder where the numbers at the end correspond to the training step. Saving checkpoints are useful for resuming training later.
+
+```py
+# resume from latest checkpoint
+trainer.train(resume_from_checkpoint=True)
+
+# resume from specific checkpoint saved in output directory
+trainer.train(resume_from_checkpoint="your-model/checkpoint-1000")
+```
+
+You can save your checkpoints (the optimizer state is not saved by default) to the Hub by setting `push_to_hub=True` in [`TrainingArguments`] to commit and push them. Other options for deciding how your checkpoints are saved are set up in the [`hub_strategy`](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.hub_strategy) parameter:
+
+* `hub_strategy="checkpoint"` pushes the latest checkpoint to a subfolder named "last-checkpoint" from which you can resume training
+* `hub_strategy="all_checkpoints"` pushes all checkpoints to the directory defined in `output_dir` (you'll see one checkpoint per folder in your model repository)
+
+When you resume training from a checkpoint, the [`Trainer`] tries to keep the Python, NumPy, and PyTorch RNG states the same as they were when the checkpoint was saved. But because PyTorch has various non-deterministic default settings, the RNG states aren't guaranteed to be the same. If you want to enable full determinism, take a look at the [Controlling sources of randomness](https://pytorch.org/docs/stable/notes/randomness#controlling-sources-of-randomness) guide to learn what you can enable to make your training fully deterministic. Keep in mind though that by making certain settings deterministic, training may be slower.
+
+## Customize the Trainer
+
+While the [`Trainer`] class is designed to be accessible and easy-to-use, it also offers a lot of customizability for more adventurous users. Many of the [`Trainer`]'s method can be subclassed and overridden to support the functionality you want, without having to rewrite the entire training loop from scratch to accommodate it. These methods include:
+
+* [`~Trainer.get_train_dataloader`] creates a training DataLoader
+* [`~Trainer.get_eval_dataloader`] creates an evaluation DataLoader
+* [`~Trainer.get_test_dataloader`] creates a test DataLoader
+* [`~Trainer.log`] logs information on the various objects that watch training
+* [`~Trainer.create_optimizer_and_scheduler`] creates an optimizer and learning rate scheduler if they weren't passed in the `__init__`; these can also be separately customized with [`~Trainer.create_optimizer`] and [`~Trainer.create_scheduler`] respectively
+* [`~Trainer.compute_loss`] computes the loss on a batch of training inputs
+* [`~Trainer.training_step`] performs the training step
+* [`~Trainer.prediction_step`] performs the prediction and test step
+* [`~Trainer.evaluate`] evaluates the model and returns the evaluation metrics
+* [`~Trainer.predict`] makes predictions (with metrics if labels are available) on the test set
+
+For example, if you want to customize the [`~Trainer.compute_loss`] method to use a weighted loss instead.
+
+```py
+from torch import nn
+from transformers import Trainer
+
+class CustomTrainer(Trainer):
+ def compute_loss(self, model, inputs, return_outputs=False):
+ labels = inputs.pop("labels")
+ # forward pass
+ outputs = model(**inputs)
+ logits = outputs.get("logits")
+ # compute custom loss for 3 labels with different weights
+ loss_fct = nn.CrossEntropyLoss(weight=torch.tensor([1.0, 2.0, 3.0], device=model.device))
+ loss = loss_fct(logits.view(-1, self.model.config.num_labels), labels.view(-1))
+ return (loss, outputs) if return_outputs else loss
+```
+
+### Callbacks
+
+Another option for customizing the [`Trainer`] is to use [callbacks](callbacks). Callbacks *don't change* anything in the training loop. They inspect the training loop state and then execute some action (early stopping, logging results, etc.) depending on the state. In other words, a callback can't be used to implement something like a custom loss function and you'll need to subclass and override the [`~Trainer.compute_loss`] method for that.
+
+For example, if you want to add an early stopping callback to the training loop after 10 steps.
+
+```py
+from transformers import TrainerCallback
+
+class EarlyStoppingCallback(TrainerCallback):
+ def __init__(self, num_steps=10):
+ self.num_steps = num_steps
+
+ def on_step_end(self, args, state, control, **kwargs):
+ if state.global_step >= self.num_steps:
+ return {"should_training_stop": True}
+ else:
+ return {}
+```
+
+Then pass it to the [`Trainer`]'s `callback` parameter.
+
+```py
+from transformers import Trainer
+
+trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=dataset["train"],
+ eval_dataset=dataset["test"],
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics,
+ callbacks=[EarlyStoppingCallback()],
+)
+```
+
+## Logging
+
+
+
+Check out the [logging](./main_classes/logging) API reference for more information about the different logging levels.
+
+
+
+The [`Trainer`] is set to `logging.INFO` by default which reports errors, warnings, and other basic information. A [`Trainer`] replica - in distributed environments - is set to `logging.WARNING` which only reports errors and warnings. You can change the logging level with the [`log_level`](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.log_level) and [`log_level_replica`](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.log_level_replica) parameters in [`TrainingArguments`].
+
+To configure the log level setting for each node, use the [`log_on_each_node`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.log_on_each_node) parameter to determine whether to use the log level on each node or only on the main node.
+
+
+
+[`Trainer`] sets the log level separately for each node in the [`Trainer.__init__`] method, so you may want to consider setting this sooner if you're using other Transformers functionalities before creating the [`Trainer`] object.
+
+
+
+For example, to set your main code and modules to use the same log level according to each node:
+
+```py
+logger = logging.getLogger(__name__)
+
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+)
+
+log_level = training_args.get_process_log_level()
+logger.setLevel(log_level)
+datasets.utils.logging.set_verbosity(log_level)
+transformers.utils.logging.set_verbosity(log_level)
+
+trainer = Trainer(...)
+```
+
+Use different combinations of `log_level` and `log_level_replica` to configure what gets logged on each of the nodes.
+
+
+
+
+```bash
+my_app.py ... --log_level warning --log_level_replica error
+```
+
+
+
+
+Add the `log_on_each_node 0` parameter for multi-node environments.
+
+```bash
+my_app.py ... --log_level warning --log_level_replica error --log_on_each_node 0
+
+# set to only report errors
+my_app.py ... --log_level error --log_level_replica error --log_on_each_node 0
+```
+
+
+
+
+## NEFTune
+
+[NEFTune](https://hf.co/papers/2310.05914) is a technique that can improve performance by adding noise to the embedding vectors during training. To enable it in [`Trainer`], set the `neftune_noise_alpha` parameter in [`TrainingArguments`] to control how much noise is added.
+
+```py
+from transformers import TrainingArguments, Trainer
+
+training_args = TrainingArguments(..., neftune_noise_alpha=0.1)
+trainer = Trainer(..., args=training_args)
+```
+
+NEFTune is disabled after training to restore the original embedding layer to avoid any unexpected behavior.
+
+## Liger Kernel
+
+[Liger-Kernel](https://github.com/linkedin/Liger-Kernel) Kernel is a collection of Triton kernels developed by Linkedin designed specifically for LLM training. We have implemented Hugging Face Compatible RMSNorm, RoPE, SwiGLU, CrossEntropy, FusedLinearCrossEntropy, and more to come. It can effectively increase multi-GPU training throughput by 20% and reduces memory usage by 60%. The kernel works out of the box with flash attention, PyTorch FSDP, and Microsoft DeepSpeed.
+
+
+Gain +20% throughput and reduce memory usage by 60% on LLaMA 3-8B model training. Achieve longer context lengths and larger batch sizes. It’s also useful if you want to scale up your model to multi-head training or large vocabulary sizes. Unleash multi-head training (medusa) and more. See details and examples in [Liger](https://github.com/linkedin/Liger-Kernel/tree/main/examples)
+
+
+First make sure to install Liger official repository:
+```bash
+pip install liger-kernel
+```
+
+You should pass `use_liger_kernel=True` to apply liger kernel on your model, for example:
+
+```py
+from transformers import TrainingArguments
+
+training_args = TrainingArguments(
+ output_dir="your-model",
+ learning_rate=2e-5,
+ per_device_train_batch_size=16,
+ per_device_eval_batch_size=16,
+ num_train_epochs=2,
+ weight_decay=0.01,
+ eval_strategy="epoch",
+ save_strategy="epoch",
+ load_best_model_at_end=True,
+ push_to_hub=True,
+ use_liger_kernel=True
+)
+```
+
+The kernel supports the Llama, Gemma, Mistral, and Mixtral model architectures. The most up-to-date list of supported models can be found [here](https://github.com/linkedin/Liger-Kernel). When `use_liger_kernel` is set to `True`, the corresponding layers in the original model will be patched with Liger's efficient implementation, so you don't need to do anything extra other than setting the argument value.
+
+
+## Optimizers
+
+You can choose a built-in optimizer for training using:
+
+```python
+from transformers import TrainingArguments
+training_args = TrainingArguments(..., optim="adamw_torch")
+```
+
+See [`OptimizerNames`](https://github.com/huggingface/transformers/blob/main/src/transformers/training_args.py) for a full list of choices. We include advanced examples in the sections below.
+
+You can also use an arbitrary PyTorch optimizer via:
+
+```python
+import torch
+
+optimizer_cls = torch.optim.AdamW
+optimizer_kwargs = {
+ "lr": 4e-3,
+ "betas": (0.9, 0.999),
+ "weight_decay": 0.05,
+}
+
+from transformers import Trainer
+trainer = Trainer(..., optimizer_cls_and_kwargs=(optimizer_cls, optimizer_kwargs))
+```
+
+### GaLore
+
+Gradient Low-Rank Projection (GaLore) is a memory-efficient low-rank training strategy that allows full-parameter learning but is more memory-efficient than common low-rank adaptation methods, such as LoRA.
+
+First make sure to install GaLore official repository:
+
+```bash
+pip install galore-torch
+```
+
+Then simply add one of `["galore_adamw", "galore_adafactor", "galore_adamw_8bit"]` in `optim` together with `optim_target_modules`, which can be a list of strings, regex or full path corresponding to the target module names you want to adapt. Below is an end-to-end example script (make sure to `pip install trl datasets`):
+
+```python
+import torch
+import datasets
+import trl
+
+from transformers import TrainingArguments, AutoConfig, AutoTokenizer, AutoModelForCausalLM
+
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+args = TrainingArguments(
+ output_dir="./test-galore",
+ max_steps=100,
+ per_device_train_batch_size=2,
+ optim="galore_adamw",
+ optim_target_modules=[r".*.attn.*", r".*.mlp.*"]
+)
+
+model_id = "google/gemma-2b"
+
+config = AutoConfig.from_pretrained(model_id)
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_config(config).to(0)
+
+trainer = trl.SFTTrainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+ dataset_text_field='text',
+ max_seq_length=512,
+)
+
+trainer.train()
+```
+
+To pass extra arguments supported by GaLore, you should pass correctly `optim_args`, for example:
+
+```python
+import torch
+import datasets
+import trl
+
+from transformers import TrainingArguments, AutoConfig, AutoTokenizer, AutoModelForCausalLM
+
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+args = TrainingArguments(
+ output_dir="./test-galore",
+ max_steps=100,
+ per_device_train_batch_size=2,
+ optim="galore_adamw",
+ optim_target_modules=[r".*.attn.*", r".*.mlp.*"],
+ optim_args="rank=64, update_proj_gap=100, scale=0.10",
+)
+
+model_id = "google/gemma-2b"
+
+config = AutoConfig.from_pretrained(model_id)
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_config(config).to(0)
+
+trainer = trl.SFTTrainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+ dataset_text_field='text',
+ max_seq_length=512,
+)
+
+trainer.train()
+```
+
+You can read more about the method in the [original repository](https://github.com/jiaweizzhao/GaLore) or the [paper](https://arxiv.org/abs/2403.03507).
+
+Currently you can only train Linear layers that are considered as GaLore layers and will use low-rank decomposition to be trained while remaining layers will be optimized in the conventional manner.
+
+Note it will take a bit of time before starting the training (~3 minutes for a 2B model on a NVIDIA A100), but training should go smoothly afterwards.
+
+You can also perform layer-wise optimization by post-pending the optimizer name with `layerwise` like below:
+
+```python
+import torch
+import datasets
+import trl
+
+from transformers import TrainingArguments, AutoConfig, AutoTokenizer, AutoModelForCausalLM
+
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+args = TrainingArguments(
+ output_dir="./test-galore",
+ max_steps=100,
+ per_device_train_batch_size=2,
+ optim="galore_adamw_layerwise",
+ optim_target_modules=[r".*.attn.*", r".*.mlp.*"]
+)
+
+model_id = "google/gemma-2b"
+
+config = AutoConfig.from_pretrained(model_id)
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_config(config).to(0)
+
+trainer = trl.SFTTrainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+ dataset_text_field='text',
+ max_seq_length=512,
+)
+
+trainer.train()
+```
+
+Note layerwise optimization is a bit experimental and does not support DDP (Distributed Data Parallel), thus you can run the training script only on a single GPU. Please see [this appropriate section](https://github.com/jiaweizzhao/GaLore?tab=readme-ov-file#train-7b-model-with-a-single-gpu-with-24gb-memory) for more details. Other features such as gradient clipping, DeepSpeed, etc might not be supported out of the box. Please [raise an issue on GitHub](https://github.com/huggingface/transformers/issues) if you encounter such issue.
+
+### LOMO optimizer
+
+The LOMO optimizers have been introduced in [Full Parameter Fine-Tuning for Large Language Models with Limited Resources](https://hf.co/papers/2306.09782) and [AdaLomo: Low-memory Optimization with Adaptive Learning Rate](https://hf.co/papers/2310.10195).
+They both consist of an efficient full-parameter fine-tuning method. These optimizers fuse the gradient computation and the parameter update in one step to reduce memory usage. Supported optimizers for LOMO are `"lomo"` and `"adalomo"`. First either install LOMO from pypi `pip install lomo-optim` or install it from source with `pip install git+https://github.com/OpenLMLab/LOMO.git`.
+
+
+
+According to the authors, it is recommended to use `AdaLomo` without `grad_norm` to get better performance and higher throughput.
+
+
+
+Below is a simple script to demonstrate how to fine-tune [google/gemma-2b](https://huggingface.co/google/gemma-2b) on IMDB dataset in full precision:
+
+```python
+import torch
+import datasets
+from transformers import TrainingArguments, AutoTokenizer, AutoModelForCausalLM
+import trl
+
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+args = TrainingArguments(
+ output_dir="./test-lomo",
+ max_steps=1000,
+ per_device_train_batch_size=4,
+ optim="adalomo",
+ gradient_checkpointing=True,
+ logging_strategy="steps",
+ logging_steps=1,
+ learning_rate=2e-6,
+ save_strategy="no",
+ run_name="lomo-imdb",
+)
+
+model_id = "google/gemma-2b"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id, low_cpu_mem_usage=True).to(0)
+
+trainer = trl.SFTTrainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+ dataset_text_field='text',
+ max_seq_length=1024,
+)
+
+trainer.train()
+```
+
+### GrokAdamW optimizer
+
+The GrokAdamW optimizer is designed to enhance training performance and stability, particularly for models that benefit from grokking signal functions. To use GrokAdamW, first install the optimizer package with `pip install grokadamw`.
+
+
+
+GrokAdamW is particularly useful for models that require advanced optimization techniques to achieve better performance and stability.
+
+
+
+Below is a simple script to demonstrate how to fine-tune [google/gemma-2b](https://huggingface.co/google/gemma-2b) on the IMDB dataset using the GrokAdamW optimizer:
+
+```python
+import torch
+import datasets
+from transformers import TrainingArguments, AutoTokenizer, AutoModelForCausalLM, Trainer
+
+# Load the IMDB dataset
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+# Define the training arguments
+args = TrainingArguments(
+ output_dir="./test-grokadamw",
+ max_steps=1000,
+ per_device_train_batch_size=4,
+ optim="grokadamw",
+ logging_strategy="steps",
+ logging_steps=1,
+ learning_rate=2e-5,
+ save_strategy="no",
+ run_name="grokadamw-imdb",
+)
+
+# Load the model and tokenizer
+model_id = "google/gemma-2b"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id, low_cpu_mem_usage=True).to(0)
+
+# Initialize the Trainer
+trainer = Trainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+)
+
+# Train the model
+trainer.train()
+```
+
+This script demonstrates how to fine-tune the `google/gemma-2b` model on the IMDB dataset using the GrokAdamW optimizer. The `TrainingArguments` are configured to use GrokAdamW, and the dataset is passed to the `Trainer` for training.
+
+### Schedule Free Optimizer
+
+The Schedule Free optimizers have been introduced in [The Road Less Scheduled](https://hf.co/papers/2405.15682).
+Schedule-Free learning replaces the momentum of the base optimizer with a combination of averaging and interpolation, to completely remove the need to anneal the learning rate with a traditional schedule.
+Supported optimizers for SFO are `"schedule_free_adamw"` and `"schedule_free_sgd"`. First install schedulefree from pypi `pip install schedulefree`.
+
+Below is a simple script to demonstrate how to fine-tune [google/gemma-2b](https://huggingface.co/google/gemma-2b) on IMDB dataset in full precision:
+
+```python
+import torch
+import datasets
+from transformers import TrainingArguments, AutoTokenizer, AutoModelForCausalLM
+import trl
+
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+args = TrainingArguments(
+ output_dir="./test-schedulefree",
+ max_steps=1000,
+ per_device_train_batch_size=4,
+ optim="schedule_free_adamw",
+ gradient_checkpointing=True,
+ logging_strategy="steps",
+ logging_steps=1,
+ learning_rate=2e-6,
+ save_strategy="no",
+ run_name="sfo-imdb",
+)
+
+model_id = "google/gemma-2b"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id, low_cpu_mem_usage=True).to(0)
+
+trainer = trl.SFTTrainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+ dataset_text_field='text',
+ max_seq_length=1024,
+)
+
+trainer.train()
+```
+
+## Accelerate and Trainer
+
+The [`Trainer`] class is powered by [Accelerate](https://hf.co/docs/accelerate), a library for easily training PyTorch models in distributed environments with support for integrations such as [FullyShardedDataParallel (FSDP)](https://pytorch.org/blog/introducing-pytorch-fully-sharded-data-parallel-api/) and [DeepSpeed](https://www.deepspeed.ai/).
+
+
+
+Learn more about FSDP sharding strategies, CPU offloading, and more with the [`Trainer`] in the [Fully Sharded Data Parallel](fsdp) guide.
+
+
+
+To use Accelerate with [`Trainer`], run the [`accelerate.config`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-config) command to set up training for your training environment. This command creates a `config_file.yaml` that'll be used when you launch your training script. For example, some example configurations you can setup are:
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+distributed_type: MULTI_GPU
+downcast_bf16: 'no'
+gpu_ids: all
+machine_rank: 0 #change rank as per the node
+main_process_ip: 192.168.20.1
+main_process_port: 9898
+main_training_function: main
+mixed_precision: fp16
+num_machines: 2
+num_processes: 8
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+distributed_type: FSDP
+downcast_bf16: 'no'
+fsdp_config:
+ fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
+ fsdp_backward_prefetch_policy: BACKWARD_PRE
+ fsdp_forward_prefetch: true
+ fsdp_offload_params: false
+ fsdp_sharding_strategy: 1
+ fsdp_state_dict_type: FULL_STATE_DICT
+ fsdp_sync_module_states: true
+ fsdp_transformer_layer_cls_to_wrap: BertLayer
+ fsdp_use_orig_params: true
+machine_rank: 0
+main_training_function: main
+mixed_precision: bf16
+num_machines: 1
+num_processes: 2
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ deepspeed_config_file: /home/user/configs/ds_zero3_config.json
+ zero3_init_flag: true
+distributed_type: DEEPSPEED
+downcast_bf16: 'no'
+machine_rank: 0
+main_training_function: main
+num_machines: 1
+num_processes: 4
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ gradient_accumulation_steps: 1
+ gradient_clipping: 0.7
+ offload_optimizer_device: cpu
+ offload_param_device: cpu
+ zero3_init_flag: true
+ zero_stage: 2
+distributed_type: DEEPSPEED
+downcast_bf16: 'no'
+machine_rank: 0
+main_training_function: main
+mixed_precision: bf16
+num_machines: 1
+num_processes: 4
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+
+The [`accelerate_launch`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-launch) command is the recommended way to launch your training script on a distributed system with Accelerate and [`Trainer`] with the parameters specified in `config_file.yaml`. This file is saved to the Accelerate cache folder and automatically loaded when you run `accelerate_launch`.
+
+For example, to run the [run_glue.py](https://github.com/huggingface/transformers/blob/f4db565b695582891e43a5e042e5d318e28f20b8/examples/pytorch/text-classification/run_glue.py#L4) training script with the FSDP configuration:
+
+```bash
+accelerate launch \
+ ./examples/pytorch/text-classification/run_glue.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 16 \
+ --learning_rate 5e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/ \
+ --overwrite_output_dir
+```
+
+You could also specify the parameters from the `config_file.yaml` file directly in the command line:
+
+```bash
+accelerate launch --num_processes=2 \
+ --use_fsdp \
+ --mixed_precision=bf16 \
+ --fsdp_auto_wrap_policy=TRANSFORMER_BASED_WRAP \
+ --fsdp_transformer_layer_cls_to_wrap="BertLayer" \
+ --fsdp_sharding_strategy=1 \
+ --fsdp_state_dict_type=FULL_STATE_DICT \
+ ./examples/pytorch/text-classification/run_glue.py
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 16 \
+ --learning_rate 5e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/ \
+ --overwrite_output_dir
+```
+
+Check out the [Launching your Accelerate scripts](https://huggingface.co/docs/accelerate/basic_tutorials/launch) tutorial to learn more about `accelerate_launch` and custom configurations.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/training.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/training.md
new file mode 100644
index 0000000000000000000000000000000000000000..fa6ef0c0da6e4b3e8198846cb87bac45dabc857a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/training.md
@@ -0,0 +1,439 @@
+
+
+# Fine-tune a pretrained model
+
+[[open-in-colab]]
+
+There are significant benefits to using a pretrained model. It reduces computation costs, your carbon footprint, and allows you to use state-of-the-art models without having to train one from scratch. 🤗 Transformers provides access to thousands of pretrained models for a wide range of tasks. When you use a pretrained model, you train it on a dataset specific to your task. This is known as fine-tuning, an incredibly powerful training technique. In this tutorial, you will fine-tune a pretrained model with a deep learning framework of your choice:
+
+* Fine-tune a pretrained model with 🤗 Transformers [`Trainer`].
+* Fine-tune a pretrained model in TensorFlow with Keras.
+* Fine-tune a pretrained model in native PyTorch.
+
+
+
+
+
+You will see a warning about some of the pretrained weights not being used and some weights being randomly
+initialized. Don't worry, this is completely normal! The pretrained head of the BERT model is discarded, and replaced with a randomly initialized classification head. You will fine-tune this new model head on your sequence classification task, transferring the knowledge of the pretrained model to it.
+
+
+
+### Training hyperparameters
+
+Next, create a [`TrainingArguments`] class which contains all the hyperparameters you can tune as well as flags for activating different training options. For this tutorial you can start with the default training [hyperparameters](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments), but feel free to experiment with these to find your optimal settings.
+
+Specify where to save the checkpoints from your training:
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(output_dir="test_trainer")
+```
+
+### Evaluate
+
+[`Trainer`] does not automatically evaluate model performance during training. You'll need to pass [`Trainer`] a function to compute and report metrics. The [🤗 Evaluate](https://huggingface.co/docs/evaluate/index) library provides a simple [`accuracy`](https://huggingface.co/spaces/evaluate-metric/accuracy) function you can load with the [`evaluate.load`] (see this [quicktour](https://huggingface.co/docs/evaluate/a_quick_tour) for more information) function:
+
+```py
+>>> import numpy as np
+>>> import evaluate
+
+>>> metric = evaluate.load("accuracy")
+```
+
+Call [`~evaluate.compute`] on `metric` to calculate the accuracy of your predictions. Before passing your predictions to `compute`, you need to convert the logits to predictions (remember all 🤗 Transformers models return logits):
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... predictions = np.argmax(logits, axis=-1)
+... return metric.compute(predictions=predictions, references=labels)
+```
+
+If you'd like to monitor your evaluation metrics during fine-tuning, specify the `eval_strategy` parameter in your training arguments to report the evaluation metric at the end of each epoch:
+
+```py
+>>> from transformers import TrainingArguments, Trainer
+
+>>> training_args = TrainingArguments(output_dir="test_trainer", eval_strategy="epoch")
+```
+
+### Trainer
+
+Create a [`Trainer`] object with your model, training arguments, training and test datasets, and evaluation function:
+
+```py
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... )
+```
+
+Then fine-tune your model by calling [`~transformers.Trainer.train`]:
+
+```py
+>>> trainer.train()
+```
+
+
+
+
+You don't have to pass a loss argument to your models when you `compile()` them! Hugging Face models automatically
+choose a loss that is appropriate for their task and model architecture if this argument is left blank. You can always
+override this by specifying a loss yourself if you want to!
+
+
+
+This approach works great for smaller datasets, but for larger datasets, you might find it starts to become a problem. Why?
+Because the tokenized array and labels would have to be fully loaded into memory, and because NumPy doesn’t handle
+“jagged” arrays, so every tokenized sample would have to be padded to the length of the longest sample in the whole
+dataset. That’s going to make your array even bigger, and all those padding tokens will slow down training too!
+
+### Loading data as a tf.data.Dataset
+
+If you want to avoid slowing down training, you can load your data as a `tf.data.Dataset` instead. Although you can write your own
+`tf.data` pipeline if you want, we have two convenience methods for doing this:
+
+- [`~TFPreTrainedModel.prepare_tf_dataset`]: This is the method we recommend in most cases. Because it is a method
+on your model, it can inspect the model to automatically figure out which columns are usable as model inputs, and
+discard the others to make a simpler, more performant dataset.
+- [`~datasets.Dataset.to_tf_dataset`]: This method is more low-level, and is useful when you want to exactly control how
+your dataset is created, by specifying exactly which `columns` and `label_cols` to include.
+
+Before you can use [`~TFPreTrainedModel.prepare_tf_dataset`], you will need to add the tokenizer outputs to your dataset as columns, as shown in
+the following code sample:
+
+```py
+def tokenize_dataset(data):
+ # Keys of the returned dictionary will be added to the dataset as columns
+ return tokenizer(data["text"])
+
+
+dataset = dataset.map(tokenize_dataset)
+```
+
+Remember that Hugging Face datasets are stored on disk by default, so this will not inflate your memory usage! Once the
+columns have been added, you can stream batches from the dataset and add padding to each batch, which greatly
+reduces the number of padding tokens compared to padding the entire dataset.
+
+
+```py
+>>> tf_dataset = model.prepare_tf_dataset(dataset["train"], batch_size=16, shuffle=True, tokenizer=tokenizer)
+```
+
+Note that in the code sample above, you need to pass the tokenizer to `prepare_tf_dataset` so it can correctly pad batches as they're loaded.
+If all the samples in your dataset are the same length and no padding is necessary, you can skip this argument.
+If you need to do something more complex than just padding samples (e.g. corrupting tokens for masked language
+modelling), you can use the `collate_fn` argument instead to pass a function that will be called to transform the
+list of samples into a batch and apply any preprocessing you want. See our
+[examples](https://github.com/huggingface/transformers/tree/main/examples) or
+[notebooks](https://huggingface.co/docs/transformers/notebooks) to see this approach in action.
+
+Once you've created a `tf.data.Dataset`, you can compile and fit the model as before:
+
+```py
+model.compile(optimizer=Adam(3e-5)) # No loss argument!
+
+model.fit(tf_dataset)
+```
+
+
+
+
+
+
+
+
+Get free access to a cloud GPU if you don't have one with a hosted notebook like [Colaboratory](https://colab.research.google.com/) or [SageMaker StudioLab](https://studiolab.sagemaker.aws/).
+
+
+
+Great, now you are ready to train! 🥳
+
+### Training loop
+
+To keep track of your training progress, use the [tqdm](https://tqdm.github.io/) library to add a progress bar over the number of training steps:
+
+```py
+>>> from tqdm.auto import tqdm
+
+>>> progress_bar = tqdm(range(num_training_steps))
+
+>>> model.train()
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... outputs = model(**batch)
+... loss = outputs.loss
+... loss.backward()
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+### Evaluate
+
+Just like how you added an evaluation function to [`Trainer`], you need to do the same when you write your own training loop. But instead of calculating and reporting the metric at the end of each epoch, this time you'll accumulate all the batches with [`~evaluate.add_batch`] and calculate the metric at the very end.
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("accuracy")
+>>> model.eval()
+>>> for batch in eval_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... with torch.no_grad():
+... outputs = model(**batch)
+
+... logits = outputs.logits
+... predictions = torch.argmax(logits, dim=-1)
+... metric.add_batch(predictions=predictions, references=batch["labels"])
+
+>>> metric.compute()
+```
+
+
+
+
+
+Refer to the Performance [guide](performance) for more details about memory-saving techniques.
+
+
+
+## Unable to load a saved TensorFlow model
+
+TensorFlow's [model.save](https://www.tensorflow.org/tutorials/keras/save_and_load#save_the_entire_model) method will save the entire model - architecture, weights, training configuration - in a single file. However, when you load the model file again, you may run into an error because 🤗 Transformers may not load all the TensorFlow-related objects in the model file. To avoid issues with saving and loading TensorFlow models, we recommend you:
+
+- Save the model weights as a `h5` file extension with [`model.save_weights`](https://www.tensorflow.org/tutorials/keras/save_and_load#save_the_entire_model) and then reload the model with [`~TFPreTrainedModel.from_pretrained`]:
+
+```py
+>>> from transformers import TFPreTrainedModel
+>>> from tensorflow import keras
+
+>>> model.save_weights("some_folder/tf_model.h5")
+>>> model = TFPreTrainedModel.from_pretrained("some_folder")
+```
+
+- Save the model with [`~TFPretrainedModel.save_pretrained`] and load it again with [`~TFPreTrainedModel.from_pretrained`]:
+
+```py
+>>> from transformers import TFPreTrainedModel
+
+>>> model.save_pretrained("path_to/model")
+>>> model = TFPreTrainedModel.from_pretrained("path_to/model")
+```
+
+## ImportError
+
+Another common error you may encounter, especially if it is a newly released model, is `ImportError`:
+
+```
+ImportError: cannot import name 'ImageGPTImageProcessor' from 'transformers' (unknown location)
+```
+
+For these error types, check to make sure you have the latest version of 🤗 Transformers installed to access the most recent models:
+
+```bash
+pip install transformers --upgrade
+```
+
+## CUDA error: device-side assert triggered
+
+Sometimes you may run into a generic CUDA error about an error in the device code.
+
+```
+RuntimeError: CUDA error: device-side assert triggered
+```
+
+You should try to run the code on a CPU first to get a more descriptive error message. Add the following environment variable to the beginning of your code to switch to a CPU:
+
+```py
+>>> import os
+
+>>> os.environ["CUDA_VISIBLE_DEVICES"] = ""
+```
+
+Another option is to get a better traceback from the GPU. Add the following environment variable to the beginning of your code to get the traceback to point to the source of the error:
+
+```py
+>>> import os
+
+>>> os.environ["CUDA_LAUNCH_BLOCKING"] = "1"
+```
+
+## Incorrect output when padding tokens aren't masked
+
+In some cases, the output `hidden_state` may be incorrect if the `input_ids` include padding tokens. To demonstrate, load a model and tokenizer. You can access a model's `pad_token_id` to see its value. The `pad_token_id` may be `None` for some models, but you can always manually set it.
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+>>> import torch
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-uncased")
+>>> model.config.pad_token_id
+0
+```
+
+The following example shows the output without masking the padding tokens:
+
+```py
+>>> input_ids = torch.tensor([[7592, 2057, 2097, 2393, 9611, 2115], [7592, 0, 0, 0, 0, 0]])
+>>> output = model(input_ids)
+>>> print(output.logits)
+tensor([[ 0.0082, -0.2307],
+ [ 0.1317, -0.1683]], grad_fn=)
+```
+
+Here is the actual output of the second sequence:
+
+```py
+>>> input_ids = torch.tensor([[7592]])
+>>> output = model(input_ids)
+>>> print(output.logits)
+tensor([[-0.1008, -0.4061]], grad_fn=)
+```
+
+Most of the time, you should provide an `attention_mask` to your model to ignore the padding tokens to avoid this silent error. Now the output of the second sequence matches its actual output:
+
+
+
+By default, the tokenizer creates an `attention_mask` for you based on your specific tokenizer's defaults.
+
+
+
+```py
+>>> attention_mask = torch.tensor([[1, 1, 1, 1, 1, 1], [1, 0, 0, 0, 0, 0]])
+>>> output = model(input_ids, attention_mask=attention_mask)
+>>> print(output.logits)
+tensor([[ 0.0082, -0.2307],
+ [-0.1008, -0.4061]], grad_fn=)
+```
+
+🤗 Transformers doesn't automatically create an `attention_mask` to mask a padding token if it is provided because:
+
+- Some models don't have a padding token.
+- For some use-cases, users want a model to attend to a padding token.
+
+## ValueError: Unrecognized configuration class XYZ for this kind of AutoModel
+
+Generally, we recommend using the [`AutoModel`] class to load pretrained instances of models. This class
+can automatically infer and load the correct architecture from a given checkpoint based on the configuration. If you see
+this `ValueError` when loading a model from a checkpoint, this means the Auto class couldn't find a mapping from
+the configuration in the given checkpoint to the kind of model you are trying to load. Most commonly, this happens when a
+checkpoint doesn't support a given task.
+For instance, you'll see this error in the following example because there is no GPT2 for question answering:
+
+```py
+>>> from transformers import AutoProcessor, AutoModelForQuestionAnswering
+
+>>> processor = AutoProcessor.from_pretrained("openai-community/gpt2-medium")
+>>> model = AutoModelForQuestionAnswering.from_pretrained("openai-community/gpt2-medium")
+ValueError: Unrecognized configuration class for this kind of AutoModel: AutoModelForQuestionAnswering.
+Model type should be one of AlbertConfig, BartConfig, BertConfig, BigBirdConfig, BigBirdPegasusConfig, BloomConfig, ...
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/_config.py b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/_config.py
new file mode 100644
index 0000000000000000000000000000000000000000..f49e4e4731965a504b8da443c2cd979638cd22bb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/_config.py
@@ -0,0 +1,14 @@
+# docstyle-ignore
+INSTALL_CONTENT = """
+# Transformers installation
+! pip install transformers datasets evaluate accelerate
+# To install from source instead of the last release, comment the command above and uncomment the following one.
+# ! pip install git+https://github.com/huggingface/transformers.git
+"""
+
+notebook_first_cells = [{"type": "code", "content": INSTALL_CONTENT}]
+black_avoid_patterns = {
+ "{processor_class}": "FakeProcessorClass",
+ "{model_class}": "FakeModelClass",
+ "{object_class}": "FakeObjectClass",
+}
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/_toctree.yml b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..45dd27abaf100af249b6893ddb855505e464adc2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/_toctree.yml
@@ -0,0 +1,109 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers
+ - local: quicktour
+ title: Tour rápido
+ - local: installation
+ title: Instalación
+ title: Empezar
+- sections:
+ - local: pipeline_tutorial
+ title: Pipelines para inferencia
+ - local: autoclass_tutorial
+ title: Carga instancias preentrenadas con un AutoClass
+ - local: preprocessing
+ title: Preprocesamiento
+ - local: training
+ title: Fine-tuning a un modelo pre-entrenado
+ - local: accelerate
+ title: Entrenamiento distribuido con 🤗 Accelerate
+ - local: model_sharing
+ title: Compartir un modelo
+ title: Tutoriales
+- sections:
+ - isExpanded: false
+ sections:
+ - local: tasks/question_answering
+ title: Respuesta a preguntas
+ - local: tasks/language_modeling
+ title: Modelado de lenguaje
+ - local: tasks/summarization
+ title: Generación de resúmenes
+ - local: tasks/multiple_choice
+ title: Selección múltiple
+ - local: tasks/image_captioning
+ title: Subtítulos de imágenes
+ title: Procesamiento del Lenguaje Natural
+ - isExpanded: false
+ sections:
+ - local: tasks/asr
+ title: Reconocimiento automático del habla
+ title: Audio
+ - isExpanded: false
+ sections:
+ - local: tasks/image_classification
+ title: Clasificación de imágenes
+ title: Visión Artificial
+ title: Guías prácticas
+- sections:
+ - local: fast_tokenizers
+ title: Usa tokenizadores de 🤗 Tokenizers
+ - local: multilingual
+ title: Modelos multilingües para inferencia
+ - local: create_a_model
+ title: Crea una arquitectura personalizada
+ - local: custom_models
+ title: Compartir modelos personalizados
+ - local: run_scripts
+ title: Entrenamiento con scripts
+ - local: chat_templating
+ title: Plantillas para Modelos de Chat
+ - local: trainer
+ title: Entrenador
+ - local: sagemaker
+ title: Ejecutar el entrenamiento en Amazon SageMaker
+ - local: converting_tensorflow_models
+ title: Convertir checkpoints de TensorFlow
+ - local: serialization
+ title: Exportar a ONNX
+ - local: torchscript
+ title: Exportar a TorchScript
+ - local: community
+ title: Los recursos de la comunidad
+ title: Guías para desarrolladores
+- sections:
+ - local: performance
+ title: Descripción general
+ - local: debugging
+ title: Debugging
+ title: Rendimiento y escalabilidad
+- sections:
+ - local: add_new_pipeline
+ title: ¿Cómo puedo añadir un pipeline a 🤗 Transformers?
+ - local: pr_checks
+ title: Verificaciones en un Pull Request
+ title: Contribuir
+- sections:
+ - local: philosophy
+ title: Filosofía
+ - local: glossary
+ title: Glosario
+ - local: task_summary
+ title: Lo que 🤗 Transformers puede hacer
+ - local: tasks_explained
+ title: Como los 🤗 Transformers resuelven tareas
+ - local: tokenizer_summary
+ title: Descripción general de los tokenizadores
+ - local: attention
+ title: Mecanismos de atención
+ - local: pad_truncation
+ title: Relleno y truncamiento
+ - local: bertology
+ title: BERTología
+ - local: perplexity
+ title: Perplejidad de los modelos de longitud fija
+ - local: pipeline_webserver
+ title: Flujo de trabajo para la inferencia de los servidores web
+ - local: model_memory_anatomy
+ title: Anatomía del entrenamiento de los modelos
+ title: Guías conceptuales
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/accelerate.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/accelerate.md
new file mode 100644
index 0000000000000000000000000000000000000000..2c4063b7ca3bca9a992ca4e407f96e51bb767a75
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/accelerate.md
@@ -0,0 +1,136 @@
+
+
+# Entrenamiento distribuido con 🤗 Accelerate
+
+El paralelismo ha emergido como una estrategia para entrenar modelos grandes en hardware limitado e incrementar la velocidad de entrenamiento en varios órdenes de magnitud. En Hugging Face creamos la biblioteca [🤗 Accelerate](https://huggingface.co/docs/accelerate) para ayudar a los usuarios a entrenar modelos 🤗 Transformers en cualquier tipo de configuración distribuida, ya sea en una máquina con múltiples GPUs o en múltiples GPUs distribuidas entre muchas máquinas. En este tutorial aprenderás cómo personalizar tu bucle de entrenamiento de PyTorch nativo para poder entrenar en entornos distribuidos.
+
+## Configuración
+
+Empecemos por instalar 🤗 Accelerate:
+
+```bash
+pip install accelerate
+```
+
+Luego, importamos y creamos un objeto [`Accelerator`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator). `Accelerator` detectará automáticamente el tipo de configuración distribuida que tengas disponible e inicializará todos los componentes necesarios para el entrenamiento. No necesitas especificar el dispositivo en donde se debe colocar tu modelo.
+
+```py
+>>> from accelerate import Accelerator
+
+>>> accelerator = Accelerator()
+```
+
+## Prepárate para acelerar
+
+Pasa todos los objetos relevantes para el entrenamiento al método [`prepare`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator.prepare). Esto incluye los DataLoaders de entrenamiento y evaluación, un modelo y un optimizador:
+
+```py
+>>> train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
+... train_dataloader, eval_dataloader, model, optimizer
+... )
+```
+
+## Backward
+
+Por último, reemplaza el típico `loss.backward()` en tu bucle de entrenamiento con el método [`backward`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator.backward) de 🤗 Accelerate:
+
+```py
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... outputs = model(**batch)
+... loss = outputs.loss
+... accelerator.backward(loss)
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+Como se puede ver en el siguiente código, ¡solo necesitas adicionar cuatro líneas de código a tu bucle de entrenamiento para habilitar el entrenamiento distribuido!
+
+```diff
++ from accelerate import Accelerator
+ from transformers import AdamW, AutoModelForSequenceClassification, get_scheduler
+
++ accelerator = Accelerator()
+
+ model = AutoModelForSequenceClassification.from_pretrained(checkpoint, num_labels=2)
+ optimizer = AdamW(model.parameters(), lr=3e-5)
+
+- device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+- model.to(device)
+
++ train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
++ train_dataloader, eval_dataloader, model, optimizer
++ )
+
+ num_epochs = 3
+ num_training_steps = num_epochs * len(train_dataloader)
+ lr_scheduler = get_scheduler(
+ "linear",
+ optimizer=optimizer,
+ num_warmup_steps=0,
+ num_training_steps=num_training_steps
+ )
+
+ progress_bar = tqdm(range(num_training_steps))
+
+ model.train()
+ for epoch in range(num_epochs):
+ for batch in train_dataloader:
+- batch = {k: v.to(device) for k, v in batch.items()}
+ outputs = model(**batch)
+ loss = outputs.loss
+- loss.backward()
++ accelerator.backward(loss)
+
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ progress_bar.update(1)
+```
+
+## Entrenamiento
+
+Una vez que hayas añadido las líneas de código relevantes, inicia el entrenamiento desde un script o notebook como Colaboratory.
+
+### Entrenar con un script
+
+Si estás corriendo tu entrenamiento desde un script ejecuta el siguiente comando para crear y guardar un archivo de configuración:
+
+```bash
+accelerate config
+```
+
+Comienza el entrenamiento con:
+
+```bash
+accelerate launch train.py
+```
+
+### Entrenar con un notebook
+
+🤗 Accelerate puede correr en un notebook si, por ejemplo, estás planeando utilizar las TPUs de Colaboratory. Encierra el código responsable del entrenamiento en una función y pásalo a `notebook_launcher`:
+
+```py
+>>> from accelerate import notebook_launcher
+
+>>> notebook_launcher(training_function)
+```
+
+Para obtener más información sobre 🤗 Accelerate y sus numerosas funciones, consulta la [documentación](https://huggingface.co/docs/accelerate).
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/add_new_pipeline.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/add_new_pipeline.md
new file mode 100644
index 0000000000000000000000000000000000000000..4ccacbd18a1853e55de5cbc41849284c3bdfd492
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/add_new_pipeline.md
@@ -0,0 +1,260 @@
+
+
+# ¿Cómo puedo crear un pipeline personalizado?
+
+En esta guía, veremos cómo crear un pipeline personalizado y cómo compartirlo en el [Hub](https://hf.co/models) o añadirlo
+a la biblioteca 🤗 Transformers.
+
+En primer lugar, debes decidir las entradas que tu pipeline podrá recibir. Pueden ser strings, bytes,
+diccionarios o lo que te parezca que vaya a ser la entrada más apropiada. Intenta mantener estas entradas en un
+formato que sea tan Python puro como sea posible, puesto que esto facilita la compatibilidad (incluso con otros
+lenguajes de programación por medio de JSON). Estos serán los `inputs` (entradas) del pipeline (`preprocess`).
+
+Ahora debes definir los `outputs` (salidas). Al igual que con los `inputs`, entre más simple el formato, mejor.
+Estas serán las salidas del método `postprocess` (posprocesamiento).
+
+Empieza heredando la clase base `Pipeline` con los 4 métodos que debemos implementar: `preprocess` (preprocesamiento),
+`_forward` (ejecución), `postprocess` (posprocesamiento) y `_sanitize_parameters` (verificar parámetros).
+
+```python
+from transformers import Pipeline
+
+
+class MyPipeline(Pipeline):
+ def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "maybe_arg" in kwargs:
+ preprocess_kwargs["maybe_arg"] = kwargs["maybe_arg"]
+ return preprocess_kwargs, {}, {}
+
+ def preprocess(self, inputs, maybe_arg=2):
+ model_input = Tensor(inputs["input_ids"])
+ return {"model_input": model_input}
+
+ def _forward(self, model_inputs):
+ # model_inputs == {"model_input": model_input}
+ outputs = self.model(**model_inputs)
+ # Quizá {"logits": Tensor(...)}
+ return outputs
+
+ def postprocess(self, model_outputs):
+ best_class = model_outputs["logits"].softmax(-1)
+ return best_class
+```
+
+La estructura de este desglose es así para garantizar una compatibilidad más o menos transparente con el uso de
+CPU/GPU y el pre/posprocesamiento en CPU en varios hilos.
+
+`preprocess` tomará las entradas definidas originalmente y las convertirá en algo que se le pueda pasar al modelo.
+Podría contener más información y a menudo es un objeto `Dict` (diccionario).
+
+`_forward` contiene los detalles de la implementación y no debería ser invocado de forma directa. `forward` es el
+método preferido a utilizar pues contiene verificaciones para asegurar que todo funcione en el dispositivo correcto.
+Cualquier cosa que esté relacionada con un modelo real debería ir en el método `_forward`, todo lo demás va en
+los métodos de preprocesamiento y posprocesamiento.
+
+Los métodos `postprocess` reciben la salida `_forward` y la convierten en la salida final que decidimos
+anteriormente.
+
+`_sanitize_parameters` existe para permitir a los usuarios pasar cualesquiera parámetros cuando lo deseen, ya
+sea al momento de inicializar el pipeline `pipeline(...., maybe_arg=4)` o al momento de invocarlo
+`pipe = pipeline(...); output = pipe(...., maybe_arg=4)`.
+
+
+El método `_sanitize_parameters` devuelve 3 diccionarios de kwargs que serán pasados directamente a `preprocess`,
+`_forward` y `postprocess`. No ingreses nada si el caller no se va a invocar con parámetros adicionales.
+Esto permite mantener los parámetros por defecto de la definición de la función, lo que es más "natural".
+
+Un ejemplo clásico sería un argumento `top_k` en el posprocesamiento de una tarea de clasificación.
+
+```python
+>>> pipe = pipeline("my-new-task")
+>>> pipe("This is a test")
+[{"label": "1-star", "score": 0.8}, {"label": "2-star", "score": 0.1}, {"label": "3-star", "score": 0.05}
+{"label": "4-star", "score": 0.025}, {"label": "5-star", "score": 0.025}]
+
+>>> pipe("This is a test", top_k=2)
+[{"label": "1-star", "score": 0.8}, {"label": "2-star", "score": 0.1}]
+```
+
+Para lograrlo, actualizaremos nuestro método `postprocess` con un valor por defecto de `5` y modificaremos
+`_sanitize_parameters` para permitir este nuevo parámetro.
+
+
+```python
+def postprocess(self, model_outputs, top_k=5):
+ best_class = model_outputs["logits"].softmax(-1)
+ # Añade la lógica para manejar el top_k
+ return best_class
+
+
+def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "maybe_arg" in kwargs:
+ preprocess_kwargs["maybe_arg"] = kwargs["maybe_arg"]
+
+ postprocess_kwargs = {}
+ if "top_k" in kwargs:
+ postprocess_kwargs["top_k"] = kwargs["top_k"]
+ return preprocess_kwargs, {}, postprocess_kwargs
+```
+
+Intenta que las entradas y salidas sean muy simples e, idealmente, que puedan serializarse como JSON, pues esto
+hace el uso del pipeline muy sencillo sin que el usuario tenga que preocuparse por conocer nuevos tipos de objetos.
+También es relativamente común tener compatibilidad con muchos tipos diferentes de argumentos por facilidad de uso
+(por ejemplo, los archivos de audio pueden ser nombres de archivo, URLs o bytes).
+
+
+## Añadirlo a la lista de tareas
+
+Para registrar tu `new-task` (nueva tarea) en la lista de tareas, debes añadirla al
+`PIPELINE_REGISTRY` (registro de pipelines):
+
+```python
+from transformers.pipelines import PIPELINE_REGISTRY
+
+PIPELINE_REGISTRY.register_pipeline(
+ "new-task",
+ pipeline_class=MyPipeline,
+ pt_model=AutoModelForSequenceClassification,
+)
+```
+
+Puedes especificar un modelo por defecto si lo deseas, en cuyo caso debe venir con una versión específica (que puede ser el nombre de un branch o hash de commit, en este caso usamos `"abcdef"`), así como el tipo:
+
+```python
+PIPELINE_REGISTRY.register_pipeline(
+ "new-task",
+ pipeline_class=MyPipeline,
+ pt_model=AutoModelForSequenceClassification,
+ default={"pt": ("user/awesome_model", "abcdef")},
+ type="text", # tipo de datos que maneja: texto, audio, imagen, multi-modalidad
+)
+```
+
+## Comparte tu pipeline en el Hub
+
+Para compartir tu pipeline personalizado en el Hub, solo tienes que guardar el código personalizado de tu sub-clase
+`Pipeline` en un archivo de Python. Por ejemplo, digamos que queremos usar un pipeline personalizado para la
+clasificación de duplas de oraciones de esta forma:
+
+```py
+import numpy as np
+
+from transformers import Pipeline
+
+
+def softmax(outputs):
+ maxes = np.max(outputs, axis=-1, keepdims=True)
+ shifted_exp = np.exp(outputs - maxes)
+ return shifted_exp / shifted_exp.sum(axis=-1, keepdims=True)
+
+
+class PairClassificationPipeline(Pipeline):
+ def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "second_text" in kwargs:
+ preprocess_kwargs["second_text"] = kwargs["second_text"]
+ return preprocess_kwargs, {}, {}
+
+ def preprocess(self, text, second_text=None):
+ return self.tokenizer(text, text_pair=second_text, return_tensors=self.framework)
+
+ def _forward(self, model_inputs):
+ return self.model(**model_inputs)
+
+ def postprocess(self, model_outputs):
+ logits = model_outputs.logits[0].numpy()
+ probabilities = softmax(logits)
+
+ best_class = np.argmax(probabilities)
+ label = self.model.config.id2label[best_class]
+ score = probabilities[best_class].item()
+ logits = logits.tolist()
+ return {"label": label, "score": score, "logits": logits}
+```
+
+La implementación es independiente del framework y funcionará con modelos de PyTorch y TensorFlow. Si guardamos
+esto en un archivo llamado `pair_classification.py`, podemos importarlo y registrarlo de la siguiente manera:
+
+```py
+from pair_classification import PairClassificationPipeline
+from transformers.pipelines import PIPELINE_REGISTRY
+from transformers import AutoModelForSequenceClassification, TFAutoModelForSequenceClassification
+
+PIPELINE_REGISTRY.register_pipeline(
+ "pair-classification",
+ pipeline_class=PairClassificationPipeline,
+ pt_model=AutoModelForSequenceClassification,
+ tf_model=TFAutoModelForSequenceClassification,
+)
+```
+
+Una vez hecho esto, podemos usarlo con un modelo pre-entrenado. Por ejemplo, al modelo `sgugger/finetuned-bert-mrpc`
+se le hizo fine-tuning con el dataset MRPC, en el cual se clasifican duplas de oraciones como paráfrasis o no.
+
+```py
+from transformers import pipeline
+
+classifier = pipeline("pair-classification", model="sgugger/finetuned-bert-mrpc")
+```
+
+Ahora podemos compartirlo en el Hub usando el método `save_pretrained`:
+
+```py
+classifier.push_to_hub("test-dynamic-pipeline")
+```
+
+Esto copiará el archivo donde definiste `PairClassificationPipeline` dentro de la carpeta `"test-dynamic-pipeline"`,
+y además guardará el modelo y el tokenizer del pipeline, antes de enviar todo al repositorio
+`{your_username}/test-dynamic-pipeline`. Después de esto, cualquier persona puede usarlo siempre que usen la opción
+`trust_remote_code=True` (confiar en código remoto):
+
+```py
+from transformers import pipeline
+
+classifier = pipeline(model="{your_username}/test-dynamic-pipeline", trust_remote_code=True)
+```
+
+## Añadir el pipeline a 🤗 Transformers
+
+Si quieres contribuir tu pipeline a la biblioteca 🤗 Transformers, tendrás que añadirlo a un nuevo módulo en el
+sub-módulo `pipelines` con el código de tu pipeline. Luego, debes añadirlo a la lista de tareas definidas en
+`pipelines/__init__.py`.
+
+A continuación tienes que añadir las pruebas. Crea un nuevo archivo llamado `tests/test_pipelines_MY_PIPELINE.py`
+basándote en las pruebas existentes.
+
+La función `run_pipeline_test` será muy genérica y se correrá sobre modelos pequeños escogidos al azar sobre todas las
+arquitecturas posibles definidas en `model_mapping` y `tf_model_mapping`.
+
+Esto es muy importante para probar compatibilidades a futuro, lo que significa que si alguien añade un nuevo modelo
+para `XXXForQuestionAnswering` entonces el pipeline intentará ejecutarse con ese modelo. Ya que los modelos son aleatorios,
+es imposible verificar los valores como tales, y es por eso que hay un helper `ANY` que simplemente intentará que la
+salida tenga el mismo tipo que la salida esperada del pipeline.
+
+También *debes* implementar 2 (preferiblemente 4) pruebas:
+
+- `test_small_model_pt` : Define un (1) modelo pequeño para este pipeline (no importa si los resultados no tienen sentido)
+y prueba las salidas del pipeline. Los resultados deberían ser los mismos que en `test_small_model_tf`.
+- `test_small_model_tf` : Define un (1) modelo pequeño para este pipeline (no importa si los resultados no tienen sentido)
+y prueba las salidas del pipeline. Los resultados deberían ser los mismos que en `test_small_model_pt`.
+- `test_large_model_pt` (`optional`): Prueba el pipeline en una tarea real en la que los resultados deben tener sentido.
+Estas pruebas son lentas y deben marcarse como tales. El objetivo de esto es ejemplificar el pipeline y asegurarse de que
+no haya divergencias en versiones futuras.
+- `test_large_model_tf` (`optional`): Prueba el pipeline en una tarea real en la que los resultados deben tener sentido.
+Estas pruebas son lentas y deben marcarse como tales. El objetivo de esto es ejemplificar el pipeline y asegurarse de que
+no haya divergencias en versiones futuras.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/attention.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/attention.md
new file mode 100644
index 0000000000000000000000000000000000000000..12b774ed88622da9ec721dd3dbdd08381d589c16
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/attention.md
@@ -0,0 +1,41 @@
+
+
+# Mecanismos de atención
+
+La mayoría de los modelos transformers utilizan atención completa, en el sentido de que la matriz de atención es cuadrada. Esto puede ser un gran cuello de botella computacional cuando tienes textos largos. `Longformer` y `reformer` son modelos que intentan ser más eficientes y utilizan una versión dispersa de la matriz de atención para acelerar el entrenamiento.
+
+## Atención LSH
+
+[Reformer](https://huggingface.co/docs/transformers/model_doc/reformer) utiliza atención LSH. En el softmax(QK^t), solo los elementos más grandes (en la dimensión softmax) de la matriz QK^t van a dar contribuciones útiles. Entonces, para cada consulta q en Q, podemos considerar solo las claves k en K que estén cerca de q. Se utiliza una función hash para determinar si q y k están cerca. La máscara de atención se modifica para enmascarar el token actual (excepto en la primera posición), porque dará una consulta y una clave iguales (entonces muy similares entre sí). Dado que el hash puede ser un poco aleatorio, en la práctica se utilizan varias funciones hash (determinadas por un parámetro n_rounds) y luego se promedian juntas.
+
+## Atención local
+
+[Longformer](https://huggingface.co/docs/transformers/model_doc/longformer) utiliza atención local: a menudo, el contexto local (por ejemplo, ¿cuáles son los dos tokens a la izquierda y a la derecha?) es suficiente para tomar acción para un token dado. Además, apilando capas de atención que tienen una ventana pequeña, la última capa tendrá un campo receptivo mayor que solamente los tokens en la ventana, lo que les permite construir una representación de toda la oración.
+
+Algunos tokens de entrada preseleccionados también reciben atención global: para esos pocos tokens, la matriz de atención puede acceder a todos los tokens y este proceso es simétrico: todos los demás tokens tienen acceso a esos tokens específicos (además de los que están en su ventana local). Esto se muestra en la Figura 2d del artículo, el cual se puede apreciar un ejemplo de una máscara de atención:
+
+
+
+
+
+Recuerda, la arquitectura se refiere al esqueleto del modelo y los checkpoints son los pesos para una arquitectura dada. Por ejemplo, [BERT](https://huggingface.co/google-bert/bert-base-uncased) es una arquitectura, mientras que `google-bert/bert-base-uncased` es un checkpoint. Modelo es un término general que puede significar una arquitectura o un checkpoint.
+
+
+
+En este tutorial, aprenderás a:
+
+* Cargar un tokenizador pre-entrenado.
+* Cargar un extractor de características (feature extractor en inglés) pre-entrenado.
+* Cargar un procesador pre-entrenado.
+* Cargar un modelo pre-entrenado.
+
+## AutoTokenizer
+
+Casi cualquier tarea de Procesamiento de Lenguaje Natural comienza con un tokenizador. Un tokenizador convierte tu input a un formato que puede ser procesado por el modelo.
+
+Carga un tokenizador con [`AutoTokenizer.from_pretrained`]:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+```
+
+Luego tokeniza tu input como lo mostrado a continuación:
+
+```py
+>>> sequence = "In a hole in the ground there lived a hobbit."
+>>> print(tokenizer(sequence))
+{'input_ids': [101, 1999, 1037, 4920, 1999, 1996, 2598, 2045, 2973, 1037, 7570, 10322, 4183, 1012, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+## AutoFeatureExtractor
+
+Para tareas de audio y visión, un extractor de características procesa la señal de audio o imagen al formato de input correcto.
+
+Carga un extractor de características con [`AutoFeatureExtractor.from_pretrained`]:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained(
+... "ehcalabres/wav2vec2-lg-xlsr-en-speech-emotion-recognition"
+... )
+```
+
+## AutoProcessor
+
+Las tareas multimodales requieren un procesador que combine dos tipos de herramientas de preprocesamiento. Por ejemplo, el modelo [LayoutLMV2](model_doc/layoutlmv2) requiere que un extractor de características maneje las imágenes y que un tokenizador maneje el texto; un procesador combina ambas.
+
+Carga un procesador con [`AutoProcessor.from_pretrained`]:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("microsoft/layoutlmv2-base-uncased")
+```
+
+## AutoModel
+
+
+
+Finalmente, las clases `AutoModelFor` te permiten cargar un modelo preentrenado para una tarea dada (revisa [aquí](model_doc/auto) para conocer la lista completa de tareas disponibles). Por ejemplo, cargue un modelo para clasificación de secuencias con [`AutoModelForSequenceClassification.from_pretrained`]:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Reutiliza fácilmente el mismo checkpoint para cargar una aquitectura para alguna tarea diferente:
+
+```py
+>>> from transformers import AutoModelForTokenClassification
+
+>>> model = AutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Generalmente recomendamos utilizar las clases `AutoTokenizer` y `AutoModelFor` para cargar instancias pre-entrenadas de modelos. Ésto asegurará que cargues la arquitectura correcta en cada ocasión. En el siguiente [tutorial](preprocessing), aprende a usar tu tokenizador recién cargado, el extractor de características y el procesador para preprocesar un dataset para fine-tuning.
+
+
+Finalmente, la clase `TFAutoModelFor` te permite cargar tu modelo pre-entrenado para una tarea dada (revisa [aquí](model_doc/auto) para conocer la lista completa de tareas disponibles). Por ejemplo, carga un modelo para clasificación de secuencias con [`TFAutoModelForSequenceClassification.from_pretrained`]:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Reutiliza fácilmente el mismo checkpoint para cargar una aquitectura para alguna tarea diferente:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Generalmente recomendamos utilizar las clases `AutoTokenizer` y `TFAutoModelFor` para cargar instancias de modelos pre-entrenados. Ésto asegurará que cargues la arquitectura correcta cada vez. En el siguiente [tutorial](preprocessing), aprende a usar tu tokenizador recién cargado, el extractor de características y el procesador para preprocesar un dataset para fine-tuning.
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/bertology.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/bertology.md
new file mode 100644
index 0000000000000000000000000000000000000000..ed4e12a8d59ceb47521ab55bb40d7878a0298b46
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/bertology.md
@@ -0,0 +1,41 @@
+
+
+# BERTología
+
+Hay un creciente campo de estudio empeñado en la investigación del funcionamiento interno de los transformers de gran escala como BERT
+(que algunos llaman "BERTología"). Algunos buenos ejemplos de este campo son:
+
+
+- BERT Rediscovers the Classical NLP Pipeline por Ian Tenney, Dipanjan Das, Ellie Pavlick:
+ https://arxiv.org/abs/1905.05950
+- Are Sixteen Heads Really Better than One? por Paul Michel, Omer Levy, Graham Neubig: https://arxiv.org/abs/1905.10650
+- What Does BERT Look At? An Analysis of BERT's Attention por Kevin Clark, Urvashi Khandelwal, Omer Levy, Christopher D.
+ Manning: https://arxiv.org/abs/1906.04341
+- CAT-probing: A Metric-based Approach to Interpret How Pre-trained Models for Programming Language Attend Code Structure: https://arxiv.org/abs/2210.04633
+
+Para asistir al desarrollo de este nuevo campo, hemos incluido algunas features adicionales en los modelos BERT/GPT/GPT-2 para
+ayudar a acceder a las representaciones internas, principalmente adaptado de la gran obra de Paul Michel
+(https://arxiv.org/abs/1905.10650):
+
+
+- accediendo a todos los hidden-states de BERT/GPT/GPT-2,
+- accediendo a todos los pesos de atención para cada head de BERT/GPT/GPT-2,
+- adquiriendo los valores de salida y gradientes de las heads para poder computar la métrica de importancia de las heads y realizar la poda de heads como se explica
+ en https://arxiv.org/abs/1905.10650.
+
+Para ayudarte a entender y usar estas features, hemos añadido un script específico de ejemplo: [bertology.py](https://github.com/huggingface/transformers/tree/main/examples/research_projects/bertology/run_bertology.py) mientras extraes información y cortas un modelo pre-entrenado en
+GLUE.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/chat_templating.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/chat_templating.md
new file mode 100644
index 0000000000000000000000000000000000000000..e287c213743542779e5bfd5ac58ba38c5e1b557e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/chat_templating.md
@@ -0,0 +1,393 @@
+
+
+
+# Plantillas para Modelos de Chat
+
+## Introducción
+
+Un caso de uso cada vez más común para LLMs es **el chat**. En un contexto de chat, en lugar de continuar una única cadena de texto (como es el caso con un modelo de lenguaje estándar), el modelo continúa una conversación que consta de uno o más **mensajes**, cada uno de los cuales incluye un **rol**, como "usuario" o "asistente", así como el texto del mensaje.
+Al igual que con la tokenización, diferentes modelos esperan formatos de entrada muy diferentes para el chat. Esta es la razón por la que agregamos las plantillas de chat como una característica. Las plantillas de chat son parte del tokenizador. Especifican cómo convertir conversaciones, representadas como listas de mensajes, en una única cadena tokenizable en el formato que el modelo espera.
+Vamos a hacer esto con un ejemplo concreto utilizando el modelo `BlenderBot`. BlenderBot tiene una plantilla predeterminada extremadamente simple, que principalmente solo agrega espacios en blanco entre rondas de diálogo:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/blenderbot-400M-distill")
+
+>>> chat = [
+... {"role": "user", "content": "Hello, how are you?"},
+... {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+... {"role": "user", "content": "I'd like to show off how chat templating works!"},
+... ]
+
+>>> tokenizer.apply_chat_template(chat, tokenize=False)
+" Hello, how are you? I'm doing great. How can I help you today? I'd like to show off how chat templating works!"
+
+```
+Observa cómo todo el chat se condensa en una sola cadena. Si usamos `tokenize=True`, que es la configuración predeterminada, esa cadena también será tokenizada para nosotros. Sin embargo, para ver una plantilla más compleja en acción, usemos el modelo `mistralai/Mistral-7B-Instruct-v0.1`
+
+```python
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-Instruct-v0.1")
+
+>>> chat = [
+... {"role": "user", "content": "Hello, how are you?"},
+... {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+... {"role": "user", "content": "I'd like to show off how chat templating works!"},
+... ]
+
+>>> tokenizer.apply_chat_template(chat, tokenize=False)
+"[INST] Hello, how are you? [/INST]I'm doing great. How can I help you today? [INST] I'd like to show off how chat templating works! [/INST]"
+```
+
+Ten en cuenta que esta vez, el tokenizador ha añadido los tokens de control [INST] y [/INST] para indicar el inicio y el final de los mensajes de usuario (¡pero no de los mensajes del asistente!). Mistral-instruct fue entrenado con estos tokens, pero BlenderBot no lo fue.
+
+## ¿Cómo uso las plantillas de chat?
+
+Como puedes ver en el ejemplo anterior, las plantillas de chat son fáciles de usar. Simplemente construye una lista de mensajes, con claves de `rol` y `contenido`, y luego pásala al método [`~PreTrainedTokenizer.apply_chat_template`]. Una vez que hagas eso, ¡obtendrás una salida lista para usar! Al utilizar plantillas de chat como entrada para la generación de modelos, también es una buena idea usar `add_generation_prompt=True` para agregar una [indicación de generación](#¿Qué-son-los-"generation-prompts"?).
+
+Aquí tienes un ejemplo de cómo preparar la entrada para `model.generate()` utilizando el modelo de asistente `Zephyr`:
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+checkpoint = "HuggingFaceH4/zephyr-7b-beta"
+tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+model = AutoModelForCausalLM.from_pretrained(checkpoint) # You may want to use bfloat16 and/or move to GPU here
+
+messages = [
+ {
+ "role": "system",
+ "content": "You are a friendly chatbot who always responds in the style of a pirate",
+ },
+ {"role": "user", "content": "How many helicopters can a human eat in one sitting?"},
+ ]
+tokenized_chat = tokenizer.apply_chat_template(messages, tokenize=True, add_generation_prompt=True, return_tensors="pt")
+print(tokenizer.decode(tokenized_chat[0]))
+```
+
+Esto generará una cadena en el formato de entrada que Zephyr espera.
+
+```text
+<|system|>
+You are a friendly chatbot who always responds in the style of a pirate
+<|user|>
+How many helicopters can a human eat in one sitting?
+<|assistant|>
+```
+
+Ahora que nuestra entrada está formateada correctamente para Zephyr, podemos usar el modelo para generar una respuesta a la pregunta del usuario:
+
+```python
+outputs = model.generate(tokenized_chat, max_new_tokens=128)
+print(tokenizer.decode(outputs[0]))
+
+```
+Esto producirá:
+
+```text
+<|system|>
+You are a friendly chatbot who always responds in the style of a pirate
+<|user|>
+How many helicopters can a human eat in one sitting?
+<|assistant|>
+Matey, I'm afraid I must inform ye that humans cannot eat helicopters. Helicopters are not food, they are flying machines. Food is meant to be eaten, like a hearty plate o' grog, a savory bowl o' stew, or a delicious loaf o' bread. But helicopters, they be for transportin' and movin' around, not for eatin'. So, I'd say none, me hearties. None at all.
+```
+
+¡Arr, al final resultó ser fácil!
+
+## ¿Existe un pipeline automatizado para chats?
+
+Sí, lo hay! Nuestros canales de generación de texto admiten entradas de chat, cual facilita más facíl utilizar los modelos de chat. En el pasado, solíamos utilizar una clase dedicada "ConversationalPipeline", pero ahora ha quedado obsoleta y su funcionalidad se ha fusionado en [`TextGenerationPipeline`]. Este pipeline está diseñado para facilitar el uso de modelos de chat. Intentemos el ejemplo de `Zephyr` de nuevo, pero esta vez utilizando el pipeline:
+
+```python
+from transformers import pipeline
+
+pipe = pipeline("conversational", "HuggingFaceH4/zephyr-7b-beta")
+messages = [
+ {
+ "role": "system",
+ "content": "You are a friendly chatbot who always responds in the style of a pirate",
+ },
+ {"role": "user", "content": "How many helicopters can a human eat in one sitting?"},
+]
+print(pipe(messages, max_new_tokens=128)[0]['generated_text'][-1]) # Print the assistant's response
+```
+
+```text
+{'role': 'assistant', 'content': "Matey, I'm afraid I must inform ye that humans cannot eat helicopters. Helicopters are not food, they are flying machines. Food is meant to be eaten, like a hearty plate o' grog, a savory bowl o' stew, or a delicious loaf o' bread. But helicopters, they be for transportin' and movin' around, not for eatin'. So, I'd say none, me hearties. None at all."}
+```
+
+
+La canalización se encargará de todos los detalles de la tokenización y de llamar a `apply_chat_template` por ti. Una vez que el modelo tenga una plantilla de chat, ¡todo lo que necesitas hacer es inicializar el pipeline y pasarle la lista de mensajes!
+
+# ¿Qué son los "generation prompts"?
+
+Puede que hayas notado que el método `apply_chat_template` tiene un argumento `add_generation_prompt`. Este argumento indica a la plantilla que agregue tokens que indiquen el inicio de una respuesta del bot. Por ejemplo, considera el siguiente chat:
+
+```python
+messages = [
+ {"role": "user", "content": "Hi there!"},
+ {"role": "assistant", "content": "Nice to meet you!"},
+ {"role": "user", "content": "Can I ask a question?"}
+]
+```
+
+Así es cómo se verá esto sin un "generation prompt", usando la plantilla ChatML que vimos en el ejemplo de Zephyr:
+
+```python
+tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=False)
+"""<|im_start|>user
+Hi there!<|im_end|>
+<|im_start|>assistant
+Nice to meet you!<|im_end|>
+<|im_start|>user
+Can I ask a question?<|im_end|>
+"""
+```
+
+Y así es como se ve **con** un "generation prompt":
+
+```python
+tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+"""<|im_start|>user
+Hi there!<|im_end|>
+<|im_start|>assistant
+Nice to meet you!<|im_end|>
+<|im_start|>user
+Can I ask a question?<|im_end|>
+<|im_start|>assistant
+"""
+```
+
+Ten en cuenta que esta vez, hemos agregado los tokens que indican el inicio de una respuesta del bot. Esto asegura que cuando el modelo genere texto, escribirá una respuesta del bot en lugar de hacer algo inesperado, como continuar el mensaje del usuario. Recuerda, los modelos de chat siguen siendo solo modelos de lenguaje: están entrenados para continuar texto, ¡y el chat es solo un tipo especial de texto para ellos! Necesitas guiarlos con los tokens de control apropiados para que sepan lo que se supone que deben estar haciendo.
+
+No todos los modelos requieren "generation prompts". Algunos modelos, como BlenderBot y LLaMA, no tienen ningún token especial antes de las respuestas del bot. En estos casos, el argumento `add_generation_prompt` no tendrá ningún efecto. El efecto exacto que tiene `add_generation_prompt` dependerá de la plantilla que se esté utilizando.
+
+## ¿Puedo usar plantillas de chat en el entrenamiento?
+
+¡Sí! Recomendamos que apliques la plantilla de chat como un paso de preprocesamiento para tu conjunto de datos. Después de esto, simplemente puedes continuar como cualquier otra tarea de entrenamiento de modelos de lenguaje. Durante el entrenamiento, generalmente deberías establecer `add_generation_prompt=False`, porque los tokens añadidos para solicitar una respuesta del asistente no serán útiles durante el entrenamiento. Veamos un ejemplo:
+
+```python
+from transformers import AutoTokenizer
+from datasets import Dataset
+
+tokenizer = AutoTokenizer.from_pretrained("HuggingFaceH4/zephyr-7b-beta")
+
+chat1 = [
+ {"role": "user", "content": "Which is bigger, the moon or the sun?"},
+ {"role": "assistant", "content": "The sun."}
+]
+chat2 = [
+ {"role": "user", "content": "Which is bigger, a virus or a bacterium?"},
+ {"role": "assistant", "content": "A bacterium."}
+]
+
+dataset = Dataset.from_dict({"chat": [chat1, chat2]})
+dataset = dataset.map(lambda x: {"formatted_chat": tokenizer.apply_chat_template(x["chat"], tokenize=False, add_generation_prompt=False)})
+print(dataset['formatted_chat'][0])
+```
+
+Y obtenemos:
+
+```text
+<|user|>
+Which is bigger, the moon or the sun?
+<|assistant|>
+The sun.
+```
+
+Desde aquí, simplemente continúa el entrenamiento como lo harías con una tarea estándar de modelado de lenguaje, utilizando la columna `formatted_chat`.
+
+## Avanzado: ¿Cómo funcionan las plantillas de chat?
+
+La plantilla de chat para un modelo se almacena en el atributo `tokenizer.chat_template`. Si no se establece ninguna plantilla de chat, se utiliza en su lugar la plantilla predeterminada para esa clase de modelo. Echemos un vistazo a la plantilla para `BlenderBot`:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/blenderbot-400M-distill")
+
+>>> tokenizer.chat_template
+"{% for message in messages %}{% if message['role'] == 'user' %}{{ ' ' }}{% endif %}{{ message['content'] }}{% if not loop.last %}{{ ' ' }}{% endif %}{% endfor %}{{ eos_token }}"
+```
+
+¡Es un poco intimidante! Vamos a agregar algunas líneas nuevas y sangria para que sea más legible. Ten en cuenta que la primera línea nueva después de cada bloque, así como cualquier espacio en blanco anterior a un bloque, se ignoran de forma predeterminada, utilizando las banderas `trim_blocks` y `lstrip_blocks` de Jinja. Sin embargo, ¡ten cuidado! Aunque el espacio en blanco inicial en cada línea se elimina, los espacios entre bloques en la misma línea no. ¡Te recomendamos encarecidamente que verifiques que tu plantilla no esté imprimiendo espacios adicionales donde no debería estarlo!
+
+```
+{% for message in messages %}
+ {% if message['role'] == 'user' %}
+ {{ ' ' }}
+ {% endif %}
+ {{ message['content'] }}
+ {% if not loop.last %}
+ {{ ' ' }}
+ {% endif %}
+{% endfor %}
+{{ eos_token }}
+```
+
+Si nunca has visto uno de estos antes, esto es una [plantilla de Jinja](https://jinja.palletsprojects.com/en/3.1.x/templates/). Jinja es un lenguaje de plantillas que te permite escribir código simple que genera texto. En muchos aspectos, el código y la sintaxis se asemejan a Python. En Python puro, esta plantilla se vería algo así:
+
+```python
+for idx, message in enumerate(messages):
+ if message['role'] == 'user':
+ print(' ')
+ print(message['content'])
+ if not idx == len(messages) - 1: # Check for the last message in the conversation
+ print(' ')
+print(eos_token)
+```
+
+Efectivamente, la plantilla hace tres cosas:
+1. Para cada mensaje, si el mensaje es un mensaje de usuario, añade un espacio en blanco antes de él, de lo contrario no imprime nada.
+2. Añade el contenido del mensaje.
+3. Si el mensaje no es el último mensaje, añade dos espacios después de él. Después del último mensaje, imprime el token EOS.
+
+Esta es una plantilla bastante simple: no añade ningún token de control y no admite mensajes "del sistema", que son una forma común de dar al modelo directivas sobre cómo debe comportarse en la conversación posterior. ¡Pero Jinja te brinda mucha flexibilidad para hacer esas cosas! Veamos una plantilla de Jinja que pueda formatear las entradas de manera similar a la forma en que LLaMA las formatea (nota que la plantilla real de LLaMA incluye el manejo de mensajes del sistema predeterminados y el manejo de mensajes del sistema ligeramente diferentes en general; ¡no uses esta en tu código real!)
+
+```
+{% for message in messages %}
+ {% if message['role'] == 'user' %}
+ {{ bos_token + '[INST] ' + message['content'] + ' [/INST]' }}
+ {% elif message['role'] == 'system' %}
+ {{ '<>\\n' + message['content'] + '\\n< >\\n\\n' }}
+ {% elif message['role'] == 'assistant' %}
+ {{ ' ' + message['content'] + ' ' + eos_token }}
+ {% endif %}
+{% endfor %}
+```
+
+Si observas esto por un momento, puedas ver lo que esta plantilla está haciendo: añade tokens específicos basados en el "rol" de cada mensaje, que representa quién lo envió. Los mensajes de usuario, asistente y sistema son claramente distinguibles para el modelo debido a los tokens en los que están envueltos.
+
+## Avanzado: Añadiendo y editando plantillas de chat
+
+### ¿Cómo creo una plantilla de chat?
+
+Simple, solo escribe una plantilla de Jinja y establece `tokenizer.chat_template`. ¡Puede resultarte más fácil comenzar con una plantilla existente de otro modelo y simplemente editarla según tus necesidades! Por ejemplo, podríamos tomar la plantilla de LLaMA de arriba y añadir "[ASST]" y "[/ASST]" a los mensajes del asistente:
+
+```
+{% for message in messages %}
+ {% if message['role'] == 'user' %}
+ {{ bos_token + '[INST] ' + message['content'].strip() + ' [/INST]' }}
+ {% elif message['role'] == 'system' %}
+ {{ '<>\\n' + message['content'].strip() + '\\n< >\\n\\n' }}
+ {% elif message['role'] == 'assistant' %}
+ {{ '[ASST] ' + message['content'] + ' [/ASST]' + eos_token }}
+ {% endif %}
+{% endfor %}
+```
+
+Ahora, simplemente establece el atributo `tokenizer.chat_template`. ¡La próxima vez que uses [`~PreTrainedTokenizer.apply_chat_template`], se utilizará tu nueva plantilla! Este atributo se guardará en el archivo tokenizer_config.json, por lo que puedes usar [`~utils.PushToHubMixin.push_to_hub`] para cargar tu nueva plantilla en el Hub y asegurarte de que todos estén utilizando la plantilla correcta para tu modelo.
+
+```python
+template = tokenizer.chat_template
+template = template.replace("SYS", "SYSTEM") # Change the system token
+tokenizer.chat_template = template # Set the new template
+tokenizer.push_to_hub("model_name") # Upload your new template to the Hub!
+```
+
+El método [`~PreTrainedTokenizer.apply_chat_template`], que utiliza tu plantilla de chat, es llamado por la clase [`TextGenerationPipeline`], así que una vez que configures la plantilla de chat correcta, tu modelo se volverá automáticamente compatible con [`TextGenerationPipeline`].
+
+
+
+Si estás ajustando finamente un modelo para chat, además de establecer una plantilla de chat, probablemente deberías agregar cualquier nuevo token de control de chat como los tokens especiales en el tokenizador. Los tokens especiales nunca se dividen, asegurando que tus tokens de control siempre se manejen como tokens únicos en lugar de ser tokenizados en piezas. También deberías establecer el atributo `eos_token` del tokenizador con el token que marca el final de las generaciones del asistente en tu plantilla. Esto asegurará que las herramientas de generación de texto puedan determinar correctamente cuándo detener la generación de texto.
+
+
+
+### ¿Qué plantilla debería usar?
+
+Cuando establezcas la plantilla para un modelo que ya ha sido entrenado para chat, debes asegurarte de que la plantilla coincida exactamente con el formato de mensajes que el modelo vio durante el entrenamiento, o de lo contrario es probable que experimentes degradación del rendimiento. Esto es cierto incluso si estás entrenando aún más el modelo; probablemente obtendrás el mejor rendimiento si mantienes constantes los tokens de chat. Esto es muy análogo a la tokenización: generalmente obtienes el mejor rendimiento para la inferencia o el ajuste fino cuando coincides precisamente con la tokenización utilizada durante el entrenamiento.
+
+Si estás entrenando un modelo desde cero o ajustando finamente un modelo de lenguaje base para chat, por otro lado, ¡tienes mucha libertad para elegir una plantilla apropiada! Los LLM son lo suficientemente inteligentes como para aprender a manejar muchos formatos de entrada diferentes. Nuestra plantilla predeterminada para modelos que no tienen una plantilla específica de clase sigue el formato ChatML, y esta es una buena elección flexible para muchos casos de uso. Se ve así:
+
+```
+{% for message in messages %}
+ {{'<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n'}}
+{% endfor %}
+```
+
+Si te gusta esta plantilla, aquí está en forma de una sola línea, lista para copiar en tu código. La versión de una sola línea también incluye un práctico soporte para [prompts de generación](#¿Qué-son-los-"generation-prompts"?), ¡pero ten en cuenta que no añade tokens de BOS o EOS! Si tu modelo espera esos tokens, no se agregarán automáticamente por `apply_chat_template`, en otras palabras, el texto será tokenizado con `add_special_tokens=False`. Esto es para evitar posibles conflictos entre la plantilla y la lógica de `add_special_tokens`. ¡Si tu modelo espera tokens especiales, asegúrate de añadirlos a la plantilla!
+
+```python
+tokenizer.chat_template = "{% if not add_generation_prompt is defined %}{% set add_generation_prompt = false %}{% endif %}{% for message in messages %}{{'<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n'}}{% endfor %}{% if add_generation_prompt %}{{ '<|im_start|>assistant\n' }}{% endif %}"
+```
+
+Esta plantilla envuelve cada mensaje en tokens `<|im_start|>` y `<|im_end|>`, y simplemente escribe el rol como una cadena, lo que permite flexibilidad en los roles con los que entrenas. La salida se ve así:
+
+```text
+<|im_start|>system
+You are a helpful chatbot that will do its best not to say anything so stupid that people tweet about it.<|im_end|>
+<|im_start|>user
+How are you?<|im_end|>
+<|im_start|>assistant
+I'm doing great!<|im_end|>
+```
+
+Los roles "usuario", "sistema" y "asistente" son los estándar para chat, y recomendamos usarlos cuando tenga sentido, particularmente si deseas que tu modelo funcione bien con [`TextGenerationPipeline`]. Sin embargo, no estás limitado a estos roles: la plantilla es extremadamente flexible y cualquier cadena puede ser un rol.
+
+### ¡Quiero añadir algunas plantillas de chat! ¿Cómo debo empezar?
+
+Si tienes algún modelo de chat, debes establecer su atributo `tokenizer.chat_template` y probarlo usando [`~PreTrainedTokenizer.apply_chat_template`], luego subir el tokenizador actualizado al Hub. Esto se aplica incluso si no eres el propietario del modelo: si estás usando un modelo con una plantilla de chat vacía o que todavía está utilizando la plantilla predeterminada de clase, por favor abre una solicitud de extracción [pull request](https://huggingface.co/docs/hub/repositories-pull-requests-discussions) al repositorio del modelo para que este atributo se pueda establecer correctamente.
+
+Una vez que se establece el atributo, ¡eso es todo, has terminado! `tokenizer.apply_chat_template` ahora funcionará correctamente para ese modelo, ¡lo que significa que también es compatible automáticamente en lugares como `TextGenerationPipeline`!
+
+Al asegurarnos de que los modelos tengan este atributo, podemos garantizar que toda la comunidad pueda utilizar todo el poder de los modelos de código abierto. Los desajustes de formato han estado acechando el campo y dañando silenciosamente el rendimiento durante demasiado tiempo: ¡es hora de ponerles fin!
+
+## Avanzado: Consejos para escribir plantillas
+
+Si no estás familiarizado con Jinja, generalmente encontramos que la forma más fácil de escribir una plantilla de chat es primero escribir un script de Python corto que formatee los mensajes como desees, y luego convertir ese script en una plantilla.
+
+Recuerda que el manejador de plantillas recibirá el historial de conversación como una variable llamada mensajes. Cada mensaje es un diccionario con dos claves, `role` y `content`. Podrás acceder a los `mensajes` en tu plantilla tal como lo harías en Python, lo que significa que puedes recorrerlo con `{% for message in messages %}` o acceder a mensajes individuales con, por ejemplo, `{{ messages[0] }}`.
+
+También puedes usar los siguientes consejos para convertir tu código a Jinja:
+
+### Bucles For
+
+Los bucles For en Jinja se ven así:
+
+```
+{% for message in messages %}
+{{ message['content'] }}
+{% endfor %}
+```
+
+Ten en cuenta que todo lo que esté dentro del {{bloque de expresión}} se imprimirá en la salida. Puedes usar operadores como `+` para combinar cadenas dentro de bloques de expresión.
+
+### Declaraciones if
+
+Las declaraciones if en Jinja se ven así:
+
+```
+{% if message['role'] == 'user' %}
+{{ message['content'] }}
+{% endif %}
+```
+
+Observa cómo donde Python utiliza espacios en blanco para marcar el inicio y el final de los bloques `for` e `if`, Jinja requiere que los termines explícitamente con `{% endfor %}` y `{% endif %}`.
+
+### Variables especiales
+
+Dentro de tu plantilla, tendrás acceso a la lista de `mensajes`, pero también puedes acceder a varias otras variables especiales. Estas incluyen tokens especiales como `bos_token` y `eos_token`, así como la variable `add_generation_prompt` que discutimos anteriormente. También puedes usar la variable `loop` para acceder a información sobre la iteración actual del bucle, por ejemplo, usando `{% if loop.last %}` para verificar si el mensaje actual es el último mensaje en la conversación. Aquí tienes un ejemplo que combina estas ideas para agregar un prompt de generación al final de la conversación si add_generation_prompt es `True`:
+
+```
+{% if loop.last and add_generation_prompt %}
+{{ bos_token + 'Assistant:\n' }}
+{% endif %}
+```
+
+### Notas sobre los espacios en blanco
+
+Hemos intentado que Jinja ignore los espacios en blanco fuera de las {{expresiones}} tanto como sea posible. Sin embargo, ten en cuenta que Jinja es un motor de plantillas de propósito general y puede tratar el espacio en blanco entre bloques en la misma línea como significativo e imprimirlo en la salida. ¡Te recomendamos **encarecidamente** que verifiques que tu plantilla no esté imprimiendo espacios adicionales donde no debería antes de subirla!
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/community.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/community.md
new file mode 100644
index 0000000000000000000000000000000000000000..71153fbc8336f629f7db3cb32277c07a099b650f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/community.md
@@ -0,0 +1,69 @@
+
+
+# Comunidad
+
+Esta página agrupa los recursos de 🤗 Transformers desarrollados por la comunidad.
+
+## Los recursos de la comunidad:
+
+| Recurso | Descripción | Autor |
+|:----------|:-------------|------:|
+| [Hugging Face Transformers Glossary Flashcards](https://www.darigovresearch.com/huggingface-transformers-glossary-flashcards) | Un conjunto de flashcards basadas en el [Glosario de documentos de Transformers] (glosario) que se ha puesto en un formato que se puede aprender/revisar fácilmente usando [Anki](https://apps.ankiweb.net/) una fuente abierta, aplicación de multiplataforma diseñada específicamente para la retención de conocimientos a largo plazo. Ve este [Introductory video on how to use the flashcards](https://www.youtube.com/watch?v=Dji_h7PILrw). | [Darigov Research](https://www.darigovresearch.com/) |
+
+## Los cuadernos de la comunidad:
+
+| Cuaderno | Descripción | Autor | |
+|:----------|:-------------|:-------------|------:|
+| [Ajustar un transformador preentrenado para generar letras](https://github.com/AlekseyKorshuk/huggingartists) | Cómo generar letras al estilo de tu artista favorito ajustando un modelo GPT-2 | [Aleksey Korshuk](https://github.com/AlekseyKorshuk) | [](https://colab.research.google.com/github/AlekseyKorshuk/huggingartists/blob/master/huggingartists-demo.ipynb) |
+| [Entrenar T5 en Tensorflow 2](https://github.com/snapthat/TF-T5-text-to-text) | Cómo entrenar a T5 para cualquier tarea usando Tensorflow 2. Este cuaderno demuestra una tarea de preguntas y respuestas implementada en Tensorflow 2 usando SQUAD | [Muhammad Harris](https://github.com/HarrisDePerceptron) |[](https://colab.research.google.com/github/snapthat/TF-T5-text-to-text/blob/master/snapthatT5/notebooks/TF-T5-Datasets%20Training.ipynb) |
+| [Entrenar T5 en TPU](https://github.com/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb) | Cómo entrenar a T5 en SQUAD con Transformers y Nlp | [Suraj Patil](https://github.com/patil-suraj) |[](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb#scrollTo=QLGiFCDqvuil) |
+| [Ajustar T5 para Clasificación y Opción Múltiple](https://github.com/patil-suraj/exploring-T5/blob/master/t5_fine_tuning.ipynb) | Cómo ajustar T5 para clasificación y tareas de opción múltiple usando un formato de texto a texto con PyTorch Lightning | [Suraj Patil](https://github.com/patil-suraj) | [](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/t5_fine_tuning.ipynb) |
+| [Ajustar DialoGPT en nuevos conjuntos de datos e idiomas](https://github.com/ncoop57/i-am-a-nerd/blob/master/_notebooks/2020-05-12-chatbot-part-1.ipynb) | Cómo ajustar el modelo DialoGPT en un nuevo conjunto de datos para chatbots conversacionales de diálogo abierto | [Nathan Cooper](https://github.com/ncoop57) | [](https://colab.research.google.com/github/ncoop57/i-am-a-nerd/blob/master/_notebooks/2020-05-12-chatbot-part-1.ipynb) |
+| [Modelado de secuencias largas con Reformer](https://github.com/patrickvonplaten/notebooks/blob/master/PyTorch_Reformer.ipynb) | Cómo entrenar en secuencias de hasta 500,000 tokens con Reformer | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/PyTorch_Reformer.ipynb) |
+| [Ajustar BART para resumir](https://github.com/ohmeow/ohmeow_website/blob/master/_notebooks/2020-05-23-text-generation-with-blurr.ipynb) | Cómo ajustar BART para resumir con fastai usando blurr | [Wayde Gilliam](https://ohmeow.com/) | [](https://colab.research.google.com/github/ohmeow/ohmeow_website/blob/master/_notebooks/2020-05-23-text-generation-with-blurr.ipynb) |
+| [Ajustar un Transformador previamente entrenado en los tweets de cualquier persona](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb) | Cómo generar tweets al estilo de tu cuenta de Twitter favorita ajustando un modelo GPT-2 | [Boris Dayma](https://github.com/borisdayma) | [](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb) |
+| [Optimizar 🤗 modelos de Hugging Face con pesos y sesgos](https://colab.research.google.com/github/wandb/examples/blob/master/colabs/huggingface/Optimize_Hugging_Face_models_with_Weights_%26_Biases.ipynb) | Un tutorial completo que muestra la integración de W&B con Hugging Face | [Boris Dayma](https://github.com/borisdayma) | [](https://colab.research.google.com/github/wandb/examples/blob/master/colabs/huggingface/Optimize_Hugging_Face_models_with_Weights_%26_Biases.ipynb) |
+| [Preentrenar Longformer](https://github.com/allenai/longformer/blob/master/scripts/convert_model_to_long.ipynb) | Cómo construir una versión "larga" de modelos preentrenados existentes | [Iz Beltagy](https://beltagy.net) | [](https://colab.research.google.com/github/allenai/longformer/blob/master/scripts/convert_model_to_long.ipynb) |
+| [Ajustar Longformer para control de calidad](https://github.com/patil-suraj/Notebooks/blob/master/longformer_qa_training.ipynb) | Cómo ajustar el modelo antiguo para la tarea de control de calidad | [Suraj Patil](https://github.com/patil-suraj) | [](https://colab.research.google.com/github/patil-suraj/Notebooks/blob/master/longformer_qa_training.ipynb) |
+| [Evaluar modelo con 🤗nlp](https://github.com/patrickvonplaten/notebooks/blob/master/How_to_evaluate_Longformer_on_TriviaQA_using_NLP.ipynb) | Cómo evaluar longformer en TriviaQA con `nlp` | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/drive/1m7eTGlPmLRgoPkkA7rkhQdZ9ydpmsdLE?usp=sharing) |
+| [Ajustar fino de T5 para la extracción de amplitud de opinión](https://github.com/enzoampil/t5-intro/blob/master/t5_qa_training_pytorch_span_extraction.ipynb) | Cómo ajustar T5 para la extracción de intervalos de opiniones mediante un formato de texto a texto con PyTorch Lightning | [Lorenzo Ampil](https://github.com/enzoampil) | [](https://colab.research.google.com/github/enzoampil/t5-intro/blob/master/t5_qa_training_pytorch_span_extraction.ipynb) |
+| [Ajustar fino de DistilBert para la clasificación multiclase](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_multiclass_classification.ipynb) | Cómo ajustar DistilBert para la clasificación multiclase con PyTorch | [Abhishek Kumar Mishra](https://github.com/abhimishra91) | [](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_multiclass_classification.ipynb)|
+|[Ajustar BERT para la clasificación de etiquetas múltiples](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_multi_label_classification.ipynb)| Cómo ajustar BERT para la clasificación de múltiples etiquetas usando PyTorch |[Abhishek Kumar Mishra](https://github.com/abhimishra91) |[](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_multi_label_classification.ipynb)|
+|[Ajustar T5 para resumir](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_summarization_wandb.ipynb)| Cómo ajustar T5 para resumir en PyTorch y realizar un seguimiento de los experimentos con WandB |[Abhishek Kumar Mishra](https://github.com/abhimishra91) |[](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_summarization_wandb.ipynb)|
+|[Acelerar el ajuste fino en transformadores con Dynamic Padding/Bucketing](https://github.com/ELS-RD/transformers-notebook/blob/master/Divide_Hugging_Face_Transformers_training_time_by_2_or_more.ipynb)| Cómo acelerar el ajuste fino en un factor de 2 usando relleno dinámico/cubetas |[Michael Benesty](https://github.com/pommedeterresautee) |[](https://colab.research.google.com/drive/1CBfRU1zbfu7-ijiOqAAQUA-RJaxfcJoO?usp=sharing)|
+|[Preentrenar Reformer para modelado de lenguaje enmascarado](https://github.com/patrickvonplaten/notebooks/blob/master/Reformer_For_Masked_LM.ipynb)| Cómo entrenar un modelo Reformer con capas de autoatención bidireccionales | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/drive/1tzzh0i8PgDQGV3SMFUGxM7_gGae3K-uW?usp=sharing)|
+|[Ampliar y ajustar Sci-BERT](https://github.com/lordtt13/word-embeddings/blob/master/COVID-19%20Research%20Data/COVID-SciBERT.ipynb)| Cómo aumentar el vocabulario de un modelo SciBERT preentrenado de AllenAI en el conjunto de datos CORD y canalizarlo. | [Tanmay Thakur](https://github.com/lordtt13) | [](https://colab.research.google.com/drive/1rqAR40goxbAfez1xvF3hBJphSCsvXmh8)|
+|[Ajustar fino de BlenderBotSmall para resúmenes usando la API de Entrenador](https://github.com/lordtt13/transformers-experiments/blob/master/Custom%20Tasks/fine-tune-blenderbot_small-for-summarization.ipynb)| Cómo ajustar BlenderBotSmall para resumir en un conjunto de datos personalizado, utilizando la API de Entrenador. | [Tanmay Thakur](https://github.com/lordtt13) | [](https://colab.research.google.com/drive/19Wmupuls7mykSGyRN_Qo6lPQhgp56ymq?usp=sharing)|
+|[Ajustar Electra e interpreta con gradientes integrados](https://github.com/elsanns/xai-nlp-notebooks/blob/master/electra_fine_tune_interpret_captum_ig.ipynb) | Cómo ajustar Electra para el análisis de sentimientos e interpretar predicciones con Captum Integrated Gradients | [Eliza Szczechla](https://elsanns.github.io) | [](https://colab.research.google.com/github/elsanns/xai-nlp-notebooks/blob/master/electra_fine_tune_interpret_captum_ig.ipynb)|
+|[ajustar un modelo GPT-2 que no está en inglés con la clase Trainer](https://github.com/philschmid/fine-tune-GPT-2/blob/master/Fine_tune_a_non_English_GPT_2_Model_with_Huggingface.ipynb) | Cómo ajustar un modelo GPT-2 que no está en inglés con la clase Trainer | [Philipp Schmid](https://www.philschmid.de) | [](https://colab.research.google.com/github/philschmid/fine-tune-GPT-2/blob/master/Fine_tune_a_non_English_GPT_2_Model_with_Huggingface.ipynb)|
+|[Ajustar un modelo DistilBERT para la tarea de clasificación de múltiples etiquetas](https://github.com/DhavalTaunk08/Transformers_scripts/blob/master/Transformers_multilabel_distilbert.ipynb) | Cómo ajustar un modelo DistilBERT para la tarea de clasificación de múltiples etiquetas | [Dhaval Taunk](https://github.com/DhavalTaunk08) | [](https://colab.research.google.com/github/DhavalTaunk08/Transformers_scripts/blob/master/Transformers_multilabel_distilbert.ipynb)|
+|[Ajustar ALBERT para la clasificación de pares de oraciones](https://github.com/NadirEM/nlp-notebooks/blob/master/Fine_tune_ALBERT_sentence_pair_classification.ipynb) | Cómo ajustar un modelo ALBERT u otro modelo basado en BERT para la tarea de clasificación de pares de oraciones | [Nadir El Manouzi](https://github.com/NadirEM) | [](https://colab.research.google.com/github/NadirEM/nlp-notebooks/blob/master/Fine_tune_ALBERT_sentence_pair_classification.ipynb)|
+|[Ajustar a Roberta para el análisis de sentimientos](https://github.com/DhavalTaunk08/NLP_scripts/blob/master/sentiment_analysis_using_roberta.ipynb) | Cómo ajustar un modelo de Roberta para el análisis de sentimientos | [Dhaval Taunk](https://github.com/DhavalTaunk08) | [](https://colab.research.google.com/github/DhavalTaunk08/NLP_scripts/blob/master/sentiment_analysis_using_roberta.ipynb)|
+|[Evaluación de modelos de generación de preguntas](https://github.com/flexudy-pipe/qugeev) | ¿Qué tan precisas son las respuestas a las preguntas generadas por tu modelo de transformador seq2seq? | [Pascal Zoleko](https://github.com/zolekode) | [](https://colab.research.google.com/drive/1bpsSqCQU-iw_5nNoRm_crPq6FRuJthq_?usp=sharing)|
+|[Clasificar texto con DistilBERT y Tensorflow](https://github.com/peterbayerle/huggingface_notebook/blob/main/distilbert_tf.ipynb) | Cómo ajustar DistilBERT para la clasificación de texto en TensorFlow | [Peter Bayerle](https://github.com/peterbayerle) | [](https://colab.research.google.com/github/peterbayerle/huggingface_notebook/blob/main/distilbert_tf.ipynb)|
+|[Aprovechar BERT para el resumen de codificador y decodificador en CNN/Dailymail](https://github.com/patrickvonplaten/notebooks/blob/master/BERT2BERT_for_CNN_Dailymail.ipynb) | Cómo iniciar en caliente un *EncoderDecoderModel* con un punto de control *google-bert/bert-base-uncased* para resumir en CNN/Dailymail | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/BERT2BERT_for_CNN_Dailymail.ipynb)|
+|[Aprovechar RoBERTa para el resumen de codificador-decodificador en BBC XSum](https://github.com/patrickvonplaten/notebooks/blob/master/RoBERTaShared_for_BBC_XSum.ipynb) | Cómo iniciar en caliente un *EncoderDecoderModel* compartido con un punto de control *FacebookAI/roberta-base* para resumir en BBC/XSum | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/RoBERTaShared_for_BBC_XSum.ipynb)|
+|[Ajustar TAPAS en Sequential Question Answering (SQA)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) | Cómo ajustar *TapasForQuestionAnswering* con un punto de control *tapas-base* en el conjunto de datos del Sequential Question Answering (SQA) | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb)|
+|[Evaluar TAPAS en Table Fact Checking (TabFact)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Evaluating_TAPAS_on_the_Tabfact_test_set.ipynb) | Cómo evaluar un *TapasForSequenceClassification* ajustado con un punto de control *tapas-base-finetuned-tabfact* usando una combinación de 🤗 conjuntos de datos y 🤗 bibliotecas de transformadores | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Evaluating_TAPAS_on_the_Tabfact_test_set.ipynb)|
+|[Ajustar de mBART para traducción](https://colab.research.google.com/github/vasudevgupta7/huggingface-tutorials/blob/main/translation_training.ipynb) | Cómo ajustar mBART utilizando Seq2SeqTrainer para la traducción del hindi al inglés | [Vasudev Gupta](https://github.com/vasudevgupta7) | [](https://colab.research.google.com/github/vasudevgupta7/huggingface-tutorials/blob/main/translation_training.ipynb)|
+|[Ajustar LayoutLM en FUNSD (a form understanding dataset)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb) | Cómo ajustar *LayoutLMForTokenClassification* en el conjunto de datos de FUNSD para la extracción de información de documentos escaneados | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb)|
+|[Ajustar DistilGPT2 y genere texto](https://colab.research.google.com/github/tripathiaakash/DistilGPT2-Tutorial/blob/main/distilgpt2_fine_tuning.ipynb) | Cómo ajustar DistilGPT2 y generar texto | [Aakash Tripathi](https://github.com/tripathiaakash) | [](https://colab.research.google.com/github/tripathiaakash/DistilGPT2-Tutorial/blob/main/distilgpt2_fine_tuning.ipynb)|
+|[Ajustar LED en tokens de hasta 8K](https://github.com/patrickvonplaten/notebooks/blob/master/Fine_tune_Longformer_Encoder_Decoder_(LED)_for_Summarization_on_pubmed.ipynb) | Cómo ajustar LED en pubmed para resúmenes de largo alcance | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/Fine_tune_Longformer_Encoder_Decoder_(LED)_for_Summarization_on_pubmed.ipynb)|
+|[Evaluar LED en Arxiv](https://github.com/patrickvonplaten/notebooks/blob/master/LED_on_Arxiv.ipynb) | Cómo evaluar efectivamente LED en resúmenes de largo alcance | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/LED_on_Arxiv.ipynb)|
+|[Ajustar fino de LayoutLM en RVL-CDIP (un conjunto de datos de clasificación de imágenes de documentos)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb) | Cómo ajustar *LayoutLMForSequenceClassification* en el conjunto de datos RVL-CDIP para la clasificación de documentos escaneados | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb)|
+|[Decodificación Wav2Vec2 CTC con ajuste GPT2](https://github.com/voidful/huggingface_notebook/blob/main/xlsr_gpt.ipynb) | Cómo decodificar la secuencia CTC con el ajuste del modelo de lenguaje | [Eric Lam](https://github.com/voidful) | [](https://colab.research.google.com/drive/1e_z5jQHYbO2YKEaUgzb1ww1WwiAyydAj?usp=sharing)|
+|[Ajustar BART para resúmenes en dos idiomas con la clase Trainer](https://github.com/elsanns/xai-nlp-notebooks/blob/master/fine_tune_bart_summarization_two_langs.ipynb) | Cómo ajustar BART para resúmenes en dos idiomas con la clase Trainer | [Eliza Szczechla](https://github.com/elsanns) | [](https://colab.research.google.com/github/elsanns/xai-nlp-notebooks/blob/master/fine_tune_bart_summarization_two_langs.ipynb)|
+|[Evaluar Big Bird en Trivia QA](https://github.com/patrickvonplaten/notebooks/blob/master/Evaluating_Big_Bird_on_TriviaQA.ipynb) | Cómo evaluar BigBird en respuesta a preguntas de documentos largos en Trivia QA | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/Evaluating_Big_Bird_on_TriviaQA.ipynb)|
+| [Crear subtítulos de video usando Wav2Vec2](https://github.com/Muennighoff/ytclipcc/blob/main/wav2vec_youtube_captions.ipynb) | Cómo crear subtítulos de YouTube a partir de cualquier vídeo transcribiendo el audio con Wav2Vec | [Niklas Muennighoff](https://github.com/Muennighoff) |[](https://colab.research.google.com/github/Muennighoff/ytclipcc/blob/main/wav2vec_youtube_captions.ipynb) |
+| [Ajustar el transformador de visión en CIFAR-10 usando PyTorch Lightning](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_PyTorch_Lightning.ipynb) | Cómo ajustar el transformador de visión (ViT) en CIFAR-10 usando transformadores HuggingFace, conjuntos de datos y PyTorch Lightning | [Niels Rogge](https://github.com/nielsrogge) |[](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_PyTorch_Lightning.ipynb) |
+| [Ajustar el Transformador de visión en CIFAR-10 usando el 🤗 Entrenador](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_the_%F0%9F%A4%97_Trainer.ipynb) | Cómo ajustar el Vision Transformer (ViT) en CIFAR-10 usando HuggingFace Transformers, Datasets y el 🤗 Trainer | [Niels Rogge](https://github.com/nielsrogge) |[](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_the_%F0%9F%A4%97_Trainer.ipynb) |
+| [Evaluar LUKE en Open Entity, un conjunto de datos de tipificación de entidades](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_open_entity.ipynb) | Cómo evaluar *LukeForEntityClassification* en el conjunto de datos de entidad abierta | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_open_entity.ipynb) |
+| [Evaluar LUKE en TACRED, un conjunto de datos de extracción de relaciones](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_tacred.ipynb) | Cómo evaluar *LukeForEntityPairClassification* en el conjunto de datos TACRED | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_tacred.ipynb) |
+| [Evaluar LUKE en CoNLL-2003, un punto de referencia importante de NER](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_conll_2003.ipynb) | Cómo evaluar *LukeForEntitySpanClassification* en el conjunto de datos CoNLL-2003 | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_conll_2003.ipynb) |
+| [Evaluar BigBird-Pegasus en el conjunto de datos de PubMed](https://github.com/vasudevgupta7/bigbird/blob/main/notebooks/bigbird_pegasus_evaluation.ipynb) | Cómo evaluar *BigBirdPegasusForConditionalGeneration* en el conjunto de datos de PubMed | [Vasudev Gupta](https://github.com/vasudevgupta7) | [](https://colab.research.google.com/github/vasudevgupta7/bigbird/blob/main/notebooks/bigbird_pegasus_evaluation.ipynb) |
+| [Clasificación de emociones del habla con Wav2Vec2](https://github/m3hrdadfi/soxan/blob/main/notebooks/Emotion_recognition_in_Greek_speech_using_Wav2Vec2.ipynb) | Cómo aprovechar un modelo Wav2Vec2 preentrenado para la clasificación de emociones en el conjunto de datos MEGA | [Mehrdad Farahani](https://github.com/m3hrdadfi) | [](https://colab.research.google.com/github/m3hrdadfi/soxan/blob/main/notebooks/Emotion_recognition_in_Greek_speech_using_Wav2Vec2.ipynb) |
+| [Detectar objetos en una imagen con DETR](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/DETR/DETR_minimal_example_(with_DetrFeatureExtractor).ipynb) | Cómo usar un modelo entrenado *DetrForObjectDetection* para detectar objetos en una imagen y visualizar la atención | [Niels Rogge](https://github.com/NielsRogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/DETR/DETR_minimal_example_(with_DetrFeatureExtractor).ipynb) |
+| [Ajustar el DETR en un conjunto de datos de detección de objetos personalizados](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/DETR/Fine_tuning_DetrForObjectDetection_on_custom_dataset_(balloon).ipynb) | Cómo ajustar *DetrForObjectDetection* en un conjunto de datos de detección de objetos personalizados | [Niels Rogge](https://github.com/NielsRogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/DETR/Fine_tuning_DetrForObjectDetection_on_custom_dataset_(balloon).ipynb) |
+| [Ajustar T5 para el reconocimiento de entidades nombradas](https://github.com/ToluClassics/Notebooks/blob/main/T5_Ner_Finetuning.ipynb) | Cómo ajustar *T5* en una tarea de reconocimiento de entidad nombrada | [Ogundepo Odunayo](https://github.com/ToluClassics) | [](https://colab.research.google.com/drive/1obr78FY_cBmWY5ODViCmzdY6O1KB65Vc?usp=sharing) |
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/converting_tensorflow_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/converting_tensorflow_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..efd47e29dc29c6afdde3c27d66f8c4f09d51c0f1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/converting_tensorflow_models.md
@@ -0,0 +1,139 @@
+
+
+# Convertir checkpoints de Tensorflow
+
+Te proporcionamos una interfaz de línea de comando (`CLI`, por sus siglas en inglés) para convertir puntos de control (_checkpoints_) originales de Bert/GPT/GPT-2/Transformer-XL/XLNet/XLM en modelos que se puedan cargar utilizando los métodos `from_pretrained` de la biblioteca.
+
+
+
+Desde 2.3.0, el script para convertir es parte de la CLI de transformers (**transformers-cli**) disponible en cualquier instalación de transformers >= 2.3.0.
+
+La siguiente documentación refleja el formato para el comando **transformers-cli convert**.
+
+
+
+## BERT
+
+Puedes convertir cualquier checkpoint de TensorFlow para BERT (en particular, [los modelos pre-entrenados y publicados por Google](https://github.com/google-research/bert#pre-trained-models)) en un archivo de PyTorch mediante el script [convert_bert_original_tf_checkpoint_to_pytorch.py](https://github.com/huggingface/transformers/tree/main/src/transformers/models/bert/convert_bert_original_tf_checkpoint_to_pytorch.py).
+
+Esta CLI toma como entrada un checkpoint de TensorFlow (tres archivos que comienzan con `bert_model.ckpt`) y el archivo de configuración asociado (`bert_config.json`), y crea un modelo PyTorch para esta configuración, carga los pesos del checkpoint de TensorFlow en el modelo de PyTorch y guarda el modelo resultante en un archivo estándar de PyTorch que se puede importar usando `from_pretrained()` (ve el ejemplo en [Tour rápido](quicktour), [run_glue.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-classification/run_glue.py)).
+
+Solo necesitas ejecutar este script **una vez** para convertir un modelo a PyTorch. Después, puedes ignorar el checkpoint de TensorFlow (los tres archivos que comienzan con `bert_model.ckpt`), pero asegúrate de conservar el archivo de configuración (`bert_config.json`) y el archivo de vocabulario (`vocab.txt`) ya que estos también son necesarios para el modelo en PyTorch.
+
+Para ejecutar este script deberás tener instalado TensorFlow y PyTorch (`pip install tensorflow`). El resto del repositorio solo requiere PyTorch.
+
+Aquí hay un ejemplo del proceso para convertir un modelo `BERT-Base Uncased` pre-entrenado:
+
+```bash
+export BERT_BASE_DIR=/path/to/bert/uncased_L-12_H-768_A-12
+
+transformers-cli convert --model_type bert \
+ --tf_checkpoint $BERT_BASE_DIR/bert_model.ckpt \
+ --config $BERT_BASE_DIR/bert_config.json \
+ --pytorch_dump_output $BERT_BASE_DIR/pytorch_model.bin
+```
+
+Puedes descargar los modelos pre-entrenados de Google para la conversión [aquí](https://github.com/google-research/bert#pre-trained-models).
+
+## ALBERT
+
+Convierte los checkpoints del modelo ALBERT de TensorFlow a PyTorch usando el script [convert_albert_original_tf_checkpoint_to_pytorch.py](https://github.com/huggingface/transformers/tree/main/src/transformers/models/albert/convert_albert_original_tf_checkpoint_to_pytorch.py).
+
+La CLI toma como entrada un checkpoint de TensorFlow (tres archivos que comienzan con `model.ckpt-best`) y el archivo de configuración adjunto (`albert_config.json`), luego crea y guarda un modelo de PyTorch. Para ejecutar esta conversión deberás tener instalados TensorFlow y PyTorch.
+
+Aquí hay un ejemplo del proceso para convertir un modelo `ALBERT Base` pre-entrenado:
+
+```bash
+export ALBERT_BASE_DIR=/path/to/albert/albert_base
+
+transformers-cli convert --model_type albert \
+ --tf_checkpoint $ALBERT_BASE_DIR/model.ckpt-best \
+ --config $ALBERT_BASE_DIR/albert_config.json \
+ --pytorch_dump_output $ALBERT_BASE_DIR/pytorch_model.bin
+```
+
+Puedes descargar los modelos pre-entrenados de Google para la conversión [aquí](https://github.com/google-research/albert#pre-trained-models).
+
+## OpenAI GPT
+
+Este es un ejemplo del proceso para convertir un modelo OpenAI GPT pre-entrenado, asumiendo que tu checkpoint de NumPy se guarda con el mismo formato que el modelo pre-entrenado de OpenAI (más información [aquí](https://github.com/openai/finetune-transformer-lm)):
+
+```bash
+export OPENAI_GPT_CHECKPOINT_FOLDER_PATH=/path/to/openai/pretrained/numpy/weights
+
+transformers-cli convert --model_type gpt \
+ --tf_checkpoint $OPENAI_GPT_CHECKPOINT_FOLDER_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT \
+ [--config OPENAI_GPT_CONFIG] \
+ [--finetuning_task_name OPENAI_GPT_FINETUNED_TASK] \
+```
+
+## OpenAI GPT-2
+
+Aquí hay un ejemplo del proceso para convertir un modelo OpenAI GPT-2 pre-entrenado (más información [aquí](https://github.com/openai/gpt-2)):
+
+```bash
+export OPENAI_GPT2_CHECKPOINT_PATH=/path/to/openai-community/gpt2/pretrained/weights
+
+transformers-cli convert --model_type gpt2 \
+ --tf_checkpoint $OPENAI_GPT2_CHECKPOINT_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT \
+ [--config OPENAI_GPT2_CONFIG] \
+ [--finetuning_task_name OPENAI_GPT2_FINETUNED_TASK]
+```
+
+## XLNet
+
+Aquí hay un ejemplo del proceso para convertir un modelo XLNet pre-entrenado:
+
+```bash
+export TRANSFO_XL_CHECKPOINT_PATH=/path/to/xlnet/checkpoint
+export TRANSFO_XL_CONFIG_PATH=/path/to/xlnet/config
+
+transformers-cli convert --model_type xlnet \
+ --tf_checkpoint $TRANSFO_XL_CHECKPOINT_PATH \
+ --config $TRANSFO_XL_CONFIG_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT \
+ [--finetuning_task_name XLNET_FINETUNED_TASK] \
+```
+
+## XLM
+
+Aquí hay un ejemplo del proceso para convertir un modelo XLM pre-entrenado:
+
+```bash
+export XLM_CHECKPOINT_PATH=/path/to/xlm/checkpoint
+
+transformers-cli convert --model_type xlm \
+ --tf_checkpoint $XLM_CHECKPOINT_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT
+ [--config XML_CONFIG] \
+ [--finetuning_task_name XML_FINETUNED_TASK]
+```
+
+## T5
+
+Aquí hay un ejemplo del proceso para convertir un modelo T5 pre-entrenado:
+
+```bash
+export T5=/path/to/t5/uncased_L-12_H-768_A-12
+
+transformers-cli convert --model_type t5 \
+ --tf_checkpoint $T5/t5_model.ckpt \
+ --config $T5/t5_config.json \
+ --pytorch_dump_output $T5/pytorch_model.bin
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/create_a_model.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/create_a_model.md
new file mode 100644
index 0000000000000000000000000000000000000000..560fbd74e3851c73afb4ddd999528267f321795c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/create_a_model.md
@@ -0,0 +1,371 @@
+
+
+# Crea una arquitectura personalizada
+
+Una [`AutoClass`](model_doc/auto) infiere, automáticamente, la arquitectura del modelo y descarga la configuración y los pesos del modelo preentrenado. Normalmente, recomendamos usar una `AutoClass` para producir un código agnóstico a puntos de guardado o checkpoints. Sin embargo, los usuarios que quieran más control sobre los parámetros específicos de los modelos pueden crear su propio modelo 🤗 Transformers personalizado a partir de varias clases base. Esto puede ser particularmente útil para alguien que esté interesado en estudiar, entrenar o experimentar con modelos 🤗 Transformers. En esta guía vamos a profundizar en la creación de modelos personalizados sin usar `AutoClass`. Aprenderemos a:
+
+- Cargar y personalizar una configuración para un modelo.
+- Crear una arquitectura para un modelo.
+- Crear tokenizadores rápidos y lentos para textos.
+- Crear un extractor de propiedades para tareas de audio o imágenes.
+- Crear un procesador para tareas multimodales.
+
+## Configuración
+
+Una [configuración](main_classes/configuration) es un conjunto de atributos específicos de un modelo. Cada configuración de modelo tiene atributos diferentes. Por ejemplo, todos los modelos de PLN tienen los atributos `hidden_size`, `num_attention_heads`, `num_hidden_layers` y `vocab_size` en común. Estos atributos especifican el número de cabezas de atención o de capas ocultas con las que se construyen los modelos.
+
+Puedes echarle un vistazo a [DistilBERT](model_doc/distilbert) y sus atributos accediendo a [`DistilBertConfig`]:
+
+```py
+>>> from transformers import DistilBertConfig
+
+>>> config = DistilBertConfig()
+>>> print(config)
+DistilBertConfig {
+ "activation": "gelu",
+ "attention_dropout": 0.1,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+[`DistilBertConfig`] muestra todos los atributos por defecto que se han usado para construir un modelo [`DistilBertModel`] base. Todos ellos son personalizables, lo que deja espacio para poder experimentar. Por ejemplo, puedes personalizar un modelo predeterminado para:
+
+- Probar una función de activación diferente, usando el parámetro `activation`.
+- Usar un valor de abandono (también conocido como _dropout_) más alto para las probabilidades de las capas de atención, usando el parámetro `attention_dropout`.
+
+```py
+>>> my_config = DistilBertConfig(activation="relu", attention_dropout=0.4)
+>>> print(my_config)
+DistilBertConfig {
+ "activation": "relu",
+ "attention_dropout": 0.4,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+Los atributos de los modelos preentrenados pueden ser modificados con la función [`~PretrainedConfig.from_pretrained`]:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("distilbert/distilbert-base-uncased", activation="relu", attention_dropout=0.4)
+```
+
+Cuando estés satisfecho con la configuración de tu modelo, puedes guardarlo con la función [`~PretrainedConfig.save_pretrained`]. Tu configuración se guardará en un archivo JSON dentro del directorio que le especifiques como parámetro.
+
+```py
+>>> my_config.save_pretrained(save_directory="./your_model_save_path")
+```
+
+Para volver a usar el archivo de configuración, puedes cargarlo usando [`~PretrainedConfig.from_pretrained`]:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+```
+
+
+
+También puedes guardar los archivos de configuración como un diccionario; o incluso guardar solo la diferencia entre tu archivo personalizado y la configuración por defecto. Consulta la [documentación sobre configuración](main_classes/configuration) para ver más detalles.
+
+
+
+## Modelo
+
+El siguiente paso será crear un [modelo](main_classes/models). El modelo, al que a veces también nos referimos como arquitectura, es el encargado de definir cada capa y qué operaciones se realizan. Los atributos como `num_hidden_layers` de la configuración se usan para definir la arquitectura. Todos los modelos comparten una clase base, [`PreTrainedModel`], y algunos métodos comunes que se pueden usar para redimensionar los _embeddings_ o para recortar cabezas de auto-atención (también llamadas _self-attention heads_). Además, todos los modelos son subclases de [`torch.nn.Module`](https://pytorch.org/docs/stable/generated/torch.nn.Module.html), [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) o [`flax.linen.Module`](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html), lo que significa que son compatibles con su respectivo framework.
+
+
+
+
+Carga los atributos de tu configuración personalizada en el modelo de la siguiente forma:
+
+```py
+>>> from transformers import DistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+>>> model = DistilBertModel(my_config)
+```
+
+Esto crea un modelo con valores aleatorios, en lugar de crearlo con los pesos del preentrenamiento, por lo que no serás capaz de usar este modelo para nada útil hasta que no lo entrenes. El entrenamiento es un proceso costoso, tanto en cuestión de recursos como de tiempo, por lo que generalmente es mejor usar un modelo preentrenado para obtener mejores resultados más rápido, consumiendo una fracción de los recursos que un entrenamiento completo hubiera requerido.
+
+Puedes crear un modelo preentrenado con [`~PreTrainedModel.from_pretrained`]:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Cuando cargues tus pesos del preentrenamiento, el modelo por defecto se carga automáticamente si nos lo proporciona 🤗 Transformers. Sin embargo, siempre puedes reemplazar (todos o algunos de) los atributos del modelo por defecto por los tuyos:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+
+Carga los atributos de tu configuración personalizada en el modelo de la siguiente forma:
+
+```py
+>>> from transformers import TFDistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+>>> tf_model = TFDistilBertModel(my_config)
+```
+
+Esto crea un modelo con valores aleatorios, en lugar de crearlo con los pesos del preentrenamiento, por lo que no serás capaz de usar este modelo para nada útil hasta que no lo entrenes. El entrenamiento es un proceso costoso, tanto en cuestión de recursos como de tiempo, por lo que generalmente es mejor usar un modelo preentrenado para obtener mejores resultados más rápido, consumiendo solo una fracción de los recursos que un entrenamiento completo hubiera requerido.
+
+Puedes crear un modelo preentrenado con [`~TFPreTrainedModel.from_pretrained`]:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Cuando cargues tus pesos del preentrenamiento, el modelo por defecto se carga automáticamente si este nos lo proporciona 🤗 Transformers. Sin embargo, siempre puedes reemplazar (todos o algunos de) los atributos del modelo por defecto por los tuyos:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+
+### Cabezas de modelo
+
+En este punto del tutorial, tenemos un modelo DistilBERT base que devuelve los *hidden states* o estados ocultos. Los *hidden states* se pasan como parámetros de entrada a la cabeza del modelo para producir la salida. 🤗 Transformers ofrece una cabeza de modelo diferente para cada tarea, siempre y cuando el modelo sea compatible para la tarea (por ejemplo, no puedes usar DistilBERT para una tarea secuencia a secuencia como la traducción).
+
+
+
+
+
+Por ejemplo, [`DistilBertForSequenceClassification`] es un modelo DistilBERT base con una cabeza de clasificación de secuencias. La cabeza de clasificación de secuencias es una capa superior que precede a la recolección de las salidas.
+
+```py
+>>> from transformers import DistilBertForSequenceClassification
+
+>>> model = DistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Puedes reutilizar este punto de guardado o *checkpoint* para otra tarea fácilmente cambiando a una cabeza de un modelo diferente. Para una tarea de respuesta a preguntas, puedes usar la cabeza del modelo [`DistilBertForQuestionAnswering`]. La cabeza de respuesta a preguntas es similar a la de clasificación de secuencias, excepto porque consta de una capa lineal delante de la salida de los *hidden states*.
+
+
+```py
+>>> from transformers import DistilBertForQuestionAnswering
+
+>>> model = DistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+Por ejemplo, [`TFDistilBertForSequenceClassification`] es un modelo DistilBERT base con una cabeza de clasificación de secuencias. La cabeza de clasificación de secuencias es una capa superior que precede a la recolección de las salidas.
+
+```py
+>>> from transformers import TFDistilBertForSequenceClassification
+
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Puedes reutilizar este punto de guardado o *checkpoint* para otra tarea fácilmente cambiando a una cabeza de un modelo diferente. Para una tarea de respuesta a preguntas, puedes usar la cabeza del modelo [`TFDistilBertForQuestionAnswering`]. La cabeza de respuesta a preguntas es similar a la de clasificación de secuencias, excepto porque consta de una capa lineal delante de la salida de los *hidden states*.
+
+
+```py
+>>> from transformers import TFDistilBertForQuestionAnswering
+
+>>> tf_model = TFDistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+## Tokenizer
+
+La ultima clase base que debes conocer antes de usar un modelo con datos textuales es la clase [tokenizer](main_classes/tokenizer), que convierte el texto bruto en tensores. Hay dos tipos de *tokenizers* que puedes usar con 🤗 Transformers:
+
+- [`PreTrainedTokenizer`]: una implementación de un *tokenizer* hecha en Python.
+- [`PreTrainedTokenizerFast`]: un *tokenizer* de nuestra librería [🤗 Tokenizer](https://huggingface.co/docs/tokenizers/python/latest/), basada en Rust. Este tipo de *tokenizer* es bastante más rápido, especialmente durante la tokenización por lotes, gracias a estar implementado en Rust. Esta rápida tokenización también ofrece métodos adicionales como el *offset mapping*, que relaciona los tokens con sus palabras o caracteres originales.
+
+Ambos *tokenizers* son compatibles con los métodos comunes, como los de encodificación y decodificación, los métodos para añadir tokens y aquellos que manejan tokens especiales.
+
+
+
+No todos los modelos son compatibles con un *tokenizer* rápido. Échale un vistazo a esta [tabla](index#supported-frameworks) para comprobar si un modelo específico es compatible con un *tokenizer* rápido.
+
+
+
+Si has entrenado tu propio *tokenizer*, puedes crear uno desde tu archivo de “vocabulario”:
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> my_tokenizer = DistilBertTokenizer(vocab_file="my_vocab_file.txt", do_lower_case=False, padding_side="left")
+```
+
+Es importante recordar que los vocabularios que provienen de un *tokenizer* personalizado serán diferentes a los vocabularios generados por el *tokenizer* de un modelo preentrenado. Debes usar el vocabulario de un *tokenizer* preentrenado si vas a usar un modelo preentrenado, de lo contrario las entradas no tendrán sentido. Crea un *tokenizer* con el vocabulario de un modelo preentrenado usando la clase [`DistilBertTokenizer`]:
+
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> slow_tokenizer = DistilBertTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Crea un *tokenizer* rápido con la clase [`DistilBertTokenizerFast`]:
+
+
+```py
+>>> from transformers import DistilBertTokenizerFast
+
+>>> fast_tokenizer = DistilBertTokenizerFast.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+Por defecto, el [`AutoTokenizer`] intentará cargar un *tokenizer* rápido. Puedes desactivar este comportamiento cambiando el parámetro `use_fast=False` de `from_pretrained`.
+
+
+
+
+## Extractor de Características
+
+Un extractor de características procesa entradas de audio e imagen. Hereda de la clase base [`~feature_extraction_utils.FeatureExtractionMixin`] y también puede heredar de la clase [`ImageFeatureExtractionMixin`] para el procesamiento de características de las imágenes o de la clase [`SequenceFeatureExtractor`] para el procesamiento de entradas de audio.
+
+Dependiendo de si trabajas en una tarea de audio o de video, puedes crear un extractor de características asociado al modelo que estés usando. Por ejemplo, podrías crear un [`ViTFeatureExtractor`] por defecto si estás usando [ViT](model_doc/vit) para clasificación de imágenes:
+
+```py
+>>> from transformers import ViTFeatureExtractor
+
+>>> vit_extractor = ViTFeatureExtractor()
+>>> print(vit_extractor)
+ViTFeatureExtractor {
+ "do_normalize": true,
+ "do_resize": true,
+ "feature_extractor_type": "ViTFeatureExtractor",
+ "image_mean": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": 2,
+ "size": 224
+}
+```
+
+
+
+Si no estás buscando ninguna personalización en específico, usa el método `from_pretrained` para cargar los parámetros del extractor de características por defecto del modelo.
+
+
+
+Puedes modificar cualquier parámetro de [`ViTFeatureExtractor`] para crear tu extractor de características personalizado:
+
+```py
+>>> from transformers import ViTFeatureExtractor
+
+>>> my_vit_extractor = ViTFeatureExtractor(resample="PIL.Image.BOX", do_normalize=False, image_mean=[0.3, 0.3, 0.3])
+>>> print(my_vit_extractor)
+ViTFeatureExtractor {
+ "do_normalize": false,
+ "do_resize": true,
+ "feature_extractor_type": "ViTFeatureExtractor",
+ "image_mean": [
+ 0.3,
+ 0.3,
+ 0.3
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": "PIL.Image.BOX",
+ "size": 224
+}
+```
+
+Para las entradas de audio, puedes crear un [`Wav2Vec2FeatureExtractor`] y personalizar los parámetros de una forma similar:
+
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> w2v2_extractor = Wav2Vec2FeatureExtractor()
+>>> print(w2v2_extractor)
+Wav2Vec2FeatureExtractor {
+ "do_normalize": true,
+ "feature_extractor_type": "Wav2Vec2FeatureExtractor",
+ "feature_size": 1,
+ "padding_side": "right",
+ "padding_value": 0.0,
+ "return_attention_mask": false,
+ "sampling_rate": 16000
+}
+```
+
+## Procesador
+
+Para modelos que son compatibles con tareas multimodales, 🤗 Transformers ofrece una clase *procesador* que agrupa un extractor de características y un *tokenizer* en el mismo objeto. Por ejemplo, probemos a usar el procesador [`Wav2Vec2Processor`] para una tarea de reconocimiento de voz (ASR). Un ASR transcribe el audio a texto, por lo que necesitaremos un extractor de características y un *tokenizer*.
+
+Crea un extractor de características para manejar la entrada de audio:
+
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> feature_extractor = Wav2Vec2FeatureExtractor(padding_value=1.0, do_normalize=True)
+```
+
+Crea un *tokenizer* para manejar la entrada de texto:
+
+```py
+>>> from transformers import Wav2Vec2CTCTokenizer
+
+>>> tokenizer = Wav2Vec2CTCTokenizer(vocab_file="my_vocab_file.txt")
+```
+
+Puedes combinar el extractor de características y el *tokenizer* en el [`Wav2Vec2Processor`]:
+
+
+```py
+>>> from transformers import Wav2Vec2Processor
+
+>>> processor = Wav2Vec2Processor(feature_extractor=feature_extractor, tokenizer=tokenizer)
+```
+Con dos clases base (la configuración y el modelo) y una clase de preprocesamiento adicional (*tokenizer*, extractor de características o procesador), puedes crear cualquiera de los modelos compatibles con 🤗 Transformers. Cada una de estas clases son configurables, permitiéndote usar sus atributos específicos. Puedes crear un modelo para entrenarlo de una forma fácil, o modificar un modelo preentrenado disponible para especializarlo.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/custom_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/custom_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..022b50d9ba52fb97c13d72d75ec97195d803424d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/custom_models.md
@@ -0,0 +1,358 @@
+
+
+# Compartir modelos personalizados
+
+La biblioteca 🤗 Transformers está diseñada para ser fácilmente ampliable. Cada modelo está completamente codificado
+sin abstracción en una subcarpeta determinada del repositorio, por lo que puedes copiar fácilmente un archivo del modelo
+y ajustarlo según tus necesidades.
+
+Si estás escribiendo un modelo completamente nuevo, podría ser más fácil comenzar desde cero. En este tutorial, te mostraremos
+cómo escribir un modelo personalizado y su configuración para que pueda usarse dentro de Transformers, y cómo puedes compartirlo
+con la comunidad (con el código en el que se basa) para que cualquiera pueda usarlo, incluso si no está presente en la biblioteca
+🤗 Transformers.
+
+Ilustraremos todo esto con un modelo ResNet, envolviendo la clase ResNet de la [biblioteca timm](https://github.com/rwightman/pytorch-image-models) en un [`PreTrainedModel`].
+
+## Escribir una configuración personalizada
+
+Antes de adentrarnos en el modelo, primero escribamos su configuración. La configuración de un modelo es un objeto que
+contendrá toda la información necesaria para construir el modelo. Como veremos en la siguiente sección, el modelo solo puede
+tomar un `config` para ser inicializado, por lo que realmente necesitamos que ese objeto esté lo más completo posible.
+
+En nuestro ejemplo, tomaremos un par de argumentos de la clase ResNet que tal vez queramos modificar. Las diferentes
+configuraciones nos darán los diferentes tipos de ResNet que son posibles. Luego simplemente almacenamos esos argumentos
+después de verificar la validez de algunos de ellos.
+
+```python
+from transformers import PretrainedConfig
+from typing import List
+
+
+class ResnetConfig(PretrainedConfig):
+ model_type = "resnet"
+
+ def __init__(
+ self,
+ block_type="bottleneck",
+ layers: List[int] = [3, 4, 6, 3],
+ num_classes: int = 1000,
+ input_channels: int = 3,
+ cardinality: int = 1,
+ base_width: int = 64,
+ stem_width: int = 64,
+ stem_type: str = "",
+ avg_down: bool = False,
+ **kwargs,
+ ):
+ if block_type not in ["basic", "bottleneck"]:
+ raise ValueError(f"`block_type` must be 'basic' or bottleneck', got {block_type}.")
+ if stem_type not in ["", "deep", "deep-tiered"]:
+ raise ValueError(f"`stem_type` must be '', 'deep' or 'deep-tiered', got {stem_type}.")
+
+ self.block_type = block_type
+ self.layers = layers
+ self.num_classes = num_classes
+ self.input_channels = input_channels
+ self.cardinality = cardinality
+ self.base_width = base_width
+ self.stem_width = stem_width
+ self.stem_type = stem_type
+ self.avg_down = avg_down
+ super().__init__(**kwargs)
+```
+
+Las tres cosas importantes que debes recordar al escribir tu propia configuración son las siguientes:
+- tienes que heredar de `PretrainedConfig`,
+- el `__init__` de tu `PretrainedConfig` debe aceptar cualquier `kwargs`,
+- esos `kwargs` deben pasarse a la superclase `__init__`.
+
+La herencia es para asegurarte de obtener toda la funcionalidad de la biblioteca 🤗 Transformers, mientras que las otras dos
+restricciones provienen del hecho de que una `PretrainedConfig` tiene más campos que los que estás configurando. Al recargar una
+`config` con el método `from_pretrained`, esos campos deben ser aceptados por tu `config` y luego enviados a la superclase.
+
+Definir un `model_type` para tu configuración (en este caso `model_type="resnet"`) no es obligatorio, a menos que quieras
+registrar tu modelo con las clases automáticas (ver la última sección).
+
+Una vez hecho esto, puedes crear y guardar fácilmente tu configuración como lo harías con cualquier otra configuración de un
+modelo de la biblioteca. Así es como podemos crear una configuración resnet50d y guardarla:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d_config.save_pretrained("custom-resnet")
+```
+
+Esto guardará un archivo llamado `config.json` dentro de la carpeta `custom-resnet`. Luego puedes volver a cargar tu configuración
+con el método `from_pretrained`:
+
+```py
+resnet50d_config = ResnetConfig.from_pretrained("custom-resnet")
+```
+
+También puedes usar cualquier otro método de la clase [`PretrainedConfig`], como [`~PretrainedConfig.push_to_hub`], para cargar
+directamente tu configuración en el Hub.
+
+## Escribir un modelo personalizado
+
+Ahora que tenemos nuestra configuración de ResNet, podemos seguir escribiendo el modelo. En realidad escribiremos dos: una que
+extrae las características ocultas de un grupo de imágenes (como [`BertModel`]) y una que es adecuada para clasificación de
+imagenes (como [`BertForSequenceClassification`]).
+
+Como mencionamos antes, solo escribiremos un envoltura (_wrapper_) libre del modelo para simplificar este ejemplo. Lo único que debemos
+hacer antes de escribir esta clase es un mapeo entre los tipos de bloques y las clases de bloques reales. Luego se define el
+modelo desde la configuración pasando todo a la clase `ResNet`:
+
+```py
+from transformers import PreTrainedModel
+from timm.models.resnet import BasicBlock, Bottleneck, ResNet
+from .configuration_resnet import ResnetConfig
+
+
+BLOCK_MAPPING = {"basic": BasicBlock, "bottleneck": Bottleneck}
+
+
+class ResnetModel(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor):
+ return self.model.forward_features(tensor)
+```
+
+Para el modelo que clasificará las imágenes, solo cambiamos el método de avance (es decir, el método `forward`):
+
+```py
+import torch
+
+
+class ResnetModelForImageClassification(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor, labels=None):
+ logits = self.model(tensor)
+ if labels is not None:
+ loss = torch.nn.functional.cross_entropy(logits, labels)
+ return {"loss": loss, "logits": logits}
+ return {"logits": logits}
+```
+
+En ambos casos, observa cómo heredamos de `PreTrainedModel` y llamamos a la inicialización de la superclase con `config`
+(un poco como cuando escribes `torch.nn.Module`). La línea que establece `config_class` no es obligatoria, a menos
+que quieras registrar tu modelo con las clases automáticas (consulta la última sección).
+
+
+
+Si tu modelo es muy similar a un modelo dentro de la biblioteca, puedes reutilizar la misma configuración de ese modelo.
+
+
+
+Puedes hacer que tu modelo devuelva lo que quieras, pero devolver un diccionario como lo hicimos para
+`ResnetModelForImageClassification`, con el `loss` incluido cuando se pasan las etiquetas, hará que tu modelo se pueda
+usar directamente dentro de la clase [`Trainer`]. Usar otro formato de salida está bien, siempre y cuando estés planeando usar
+tu propio bucle de entrenamiento u otra biblioteca para el entrenamiento.
+
+Ahora que tenemos nuestra clase, vamos a crear un modelo:
+
+```py
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+```
+
+Nuevamente, puedes usar cualquiera de los métodos de [`PreTrainedModel`], como [`~PreTrainedModel.save_pretrained`] o
+[`~PreTrainedModel.push_to_hub`]. Usaremos el segundo en la siguiente sección y veremos cómo pasar los pesos del modelo
+con el código de nuestro modelo. Pero primero, carguemos algunos pesos previamente entrenados dentro de nuestro modelo.
+
+En tu caso de uso, probablemente estarás entrenando tu modelo personalizado con tus propios datos. Para ir rápido en este
+tutorial, usaremos la versión preentrenada de resnet50d. Dado que nuestro modelo es solo un envoltorio alrededor del resnet50d
+original, será fácil transferir esos pesos:
+
+```py
+import timm
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+Ahora veamos cómo asegurarnos de que cuando hacemos [`~PreTrainedModel.save_pretrained`] o [`~PreTrainedModel.push_to_hub`],
+se guarda el código del modelo.
+
+## Enviar el código al _Hub_
+
+
+
+Esta _API_ es experimental y puede tener algunos cambios leves en las próximas versiones.
+
+
+
+Primero, asegúrate de que tu modelo esté completamente definido en un archivo `.py`. Puedes basarte en importaciones
+relativas a otros archivos, siempre que todos los archivos estén en el mismo directorio (aún no admitimos submódulos
+para esta característica). Para nuestro ejemplo, definiremos un archivo `modeling_resnet.py` y un archivo
+`configuration_resnet.py` en una carpeta del directorio de trabajo actual llamado `resnet_model`. El archivo de configuración
+contiene el código de `ResnetConfig` y el archivo del modelo contiene el código de `ResnetModel` y
+`ResnetModelForImageClassification`.
+
+```
+.
+└── resnet_model
+ ├── __init__.py
+ ├── configuration_resnet.py
+ └── modeling_resnet.py
+```
+
+El `__init__.py` puede estar vacío, solo está ahí para que Python detecte que `resnet_model` se puede usar como un módulo.
+
+
+
+Si copias archivos del modelo desde la biblioteca, deberás reemplazar todas las importaciones relativas en la parte superior
+del archivo para importarlos desde el paquete `transformers`.
+
+
+
+Ten en cuenta que puedes reutilizar (o subclasificar) una configuración o modelo existente.
+
+Para compartir tu modelo con la comunidad, sigue estos pasos: primero importa el modelo y la configuración de ResNet desde
+los archivos recién creados:
+
+```py
+from resnet_model.configuration_resnet import ResnetConfig
+from resnet_model.modeling_resnet import ResnetModel, ResnetModelForImageClassification
+```
+
+Luego, debes decirle a la biblioteca que deseas copiar el código de esos objetos cuando usas el método `save_pretrained`
+y registrarlos correctamente con una determinada clase automática (especialmente para modelos), simplemente ejecuta:
+
+```py
+ResnetConfig.register_for_auto_class()
+ResnetModel.register_for_auto_class("AutoModel")
+ResnetModelForImageClassification.register_for_auto_class("AutoModelForImageClassification")
+```
+
+Ten en cuenta que no es necesario especificar una clase automática para la configuración (solo hay una clase automática
+para ellos, [`AutoConfig`]), pero es diferente para los modelos. Tu modelo personalizado podría ser adecuado para muchas
+tareas diferentes, por lo que debes especificar cuál de las clases automáticas es la correcta para tu modelo.
+
+A continuación, vamos a crear la configuración y los modelos como lo hicimos antes:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+Ahora, para enviar el modelo al Hub, asegúrate de haber iniciado sesión. Ejecuta en tu terminal:
+
+```bash
+huggingface-cli login
+```
+
+o desde un _notebook_:
+
+```py
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+Luego puedes ingresar a tu propio espacio (o una organización de la que seas miembro) de esta manera:
+
+```py
+resnet50d.push_to_hub("custom-resnet50d")
+```
+
+Además de los pesos del modelo y la configuración en formato json, esto también copió los archivos `.py` del modelo y la
+configuración en la carpeta `custom-resnet50d` y subió el resultado al Hub. Puedes verificar el resultado en este
+[repositorio de modelos](https://huggingface.co/sgugger/custom-resnet50d).
+
+Consulta el tutorial sobre cómo [compartir modelos](model_sharing) para obtener más información sobre el método para subir modelos al Hub.
+
+## Usar un modelo con código personalizado
+
+Puedes usar cualquier configuración, modelo o _tokenizador_ con archivos de código personalizado en tu repositorio con las
+clases automáticas y el método `from_pretrained`. Todos los archivos y códigos cargados en el Hub se analizan en busca de
+malware (consulta la documentación de [seguridad del Hub](https://huggingface.co/docs/hub/security#malware-scanning) para
+obtener más información), pero aún debes revisar el código del modelo y el autor para evitar la ejecución de código malicioso
+en tu computadora. Configura `trust_remote_code=True` para usar un modelo con código personalizado:
+
+```py
+from transformers import AutoModelForImageClassification
+
+model = AutoModelForImageClassification.from_pretrained("sgugger/custom-resnet50d", trust_remote_code=True)
+```
+
+También se recomienda encarecidamente pasar un _hash_ de confirmación como una "revisión" para asegurarte de que el autor
+de los modelos no actualizó el código con algunas líneas nuevas maliciosas (a menos que confíes plenamente en los autores
+de los modelos).
+
+```py
+commit_hash = "ed94a7c6247d8aedce4647f00f20de6875b5b292"
+model = AutoModelForImageClassification.from_pretrained(
+ "sgugger/custom-resnet50d", trust_remote_code=True, revision=commit_hash
+)
+```
+
+Ten en cuenta que al navegar por el historial de confirmaciones del repositorio del modelo en Hub, hay un botón para copiar
+fácilmente el hash de confirmación de cualquier _commit_.
+
+## Registrar un model con código personalizado a las clases automáticas
+
+Si estás escribiendo una biblioteca que amplía 🤗 Transformers, es posible que quieras ampliar las clases automáticas para
+incluir tu propio modelo. Esto es diferente de enviar el código al Hub en el sentido de que los usuarios necesitarán importar
+tu biblioteca para obtener los modelos personalizados (al contrario de descargar automáticamente el código del modelo desde Hub).
+
+Siempre que tu configuración tenga un atributo `model_type` que sea diferente de los tipos de modelos existentes, y que tus
+clases modelo tengan los atributos `config_class` correctos, puedes agregarlos a las clases automáticas de la siguiente manera:
+
+```py
+from transformers import AutoConfig, AutoModel, AutoModelForImageClassification
+
+AutoConfig.register("resnet", ResnetConfig)
+AutoModel.register(ResnetConfig, ResnetModel)
+AutoModelForImageClassification.register(ResnetConfig, ResnetModelForImageClassification)
+```
+
+Ten en cuenta que el primer argumento utilizado al registrar tu configuración personalizada en [`AutoConfig`] debe coincidir
+con el `model_type` de tu configuración personalizada, y el primer argumento utilizado al registrar tus modelos personalizados
+en cualquier clase del modelo automático debe coincidir con el `config_class ` de esos modelos.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/debugging.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/debugging.md
new file mode 100644
index 0000000000000000000000000000000000000000..313566753052cbf147c4d28eaaa48d0f3f9bf5df
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/debugging.md
@@ -0,0 +1,335 @@
+
+
+# Debugging
+
+## Debug de problemas de Network multi-GPU
+
+Cuando entrenas o infieres con `DistributedDataParallel` y varias GPUs, si encuentras problemas de intercomunicación entre procesos y/o nodos, puedes usar el siguiente script para diagnosticar problemas de red.
+
+```bash
+wget https://raw.githubusercontent.com/huggingface/transformers/main/scripts/distributed/torch-distributed-gpu-test.py
+```
+
+Por ejemplo, para probar cómo interactúan 2 GPUs, haz lo siguiente:
+
+```bash
+python -m torch.distributed.run --nproc_per_node 2 --nnodes 1 torch-distributed-gpu-test.py
+```
+Si ambos procesos pueden hablar entre sí y asignar la memoria de la GPU, cada uno imprimirá un status OK.
+
+Para más GPUs o nodos, ajusta los argumentos en el script.
+
+Encontrarás muchos más detalles dentro del script de diagnóstico e incluso una receta de cómo ejecutarlo en un entorno SLURM.
+
+Un nivel adicional de debug es agregar la variable de entorno `NCCL_DEBUG=INFO` de la siguiente manera:
+
+```bash
+NCCL_DEBUG=INFO python -m torch.distributed.run --nproc_per_node 2 --nnodes 1 torch-distributed-gpu-test.py
+```
+
+Esto mostrará mucha información de debug relacionada con NCCL, que luego puedes buscar online si encuentras que reporta algún problema. O si no estás seguro de cómo interpretar el output, puedes compartir el archivo de log en un Issue.
+
+
+## Detección de Underflow y Overflow
+
+
+
+Esta función está disponible actualmente sólo para PyTorch.
+
+
+
+
+
+Para el entrenamiento multi-GPU, requiere DDP (`torch.distributed.launch`).
+
+
+
+
+
+Esta función puede utilizarse con cualquier modelo basado en `nn.Module`.
+
+
+
+Si empiezas a obtener `loss=NaN` o el modelo muestra algún otro comportamiento anormal debido a `inf` o `nan` en
+activations o weights hay que descubrir dónde se produce el primer underflow o overflow y qué lo ha provocado. Por suerte
+puedes lograrlo fácilmente activando un módulo especial que hará la detección automáticamente.
+
+Si estás usando [`Trainer`], solo necesitas añadir:
+
+```bash
+--debug underflow_overflow
+```
+
+a los argumentos normales de la línea de comandos, o pasar `debug="underflow_overflow"` al crear el objeto [`TrainingArguments`].
+
+Si estás usando tu propio bucle de entrenamiento u otro Trainer puedes lograr lo mismo con:
+
+```python
+from .debug_utils import DebugUnderflowOverflow
+
+debug_overflow = DebugUnderflowOverflow(model)
+```
+
+[`~debug_utils.DebugUnderflowOverflow`] inserta hooks en el modelo que inmediatamente después de cada forward
+testeará las variables de input y output y también los weights del módulo correspondiente. Tan pronto como se detecte `inf` o
+`nan` se detecta en al menos un elemento de las activations o weights, el programa afirmará e imprimirá un informe
+como este (esto fue capturado con `google/mt5-small` bajo fp16 mixed precision):
+
+```
+Detected inf/nan during batch_number=0
+Last 21 forward frames:
+abs min abs max metadata
+ encoder.block.1.layer.1.DenseReluDense.dropout Dropout
+0.00e+00 2.57e+02 input[0]
+0.00e+00 2.85e+02 output
+[...]
+ encoder.block.2.layer.0 T5LayerSelfAttention
+6.78e-04 3.15e+03 input[0]
+2.65e-04 3.42e+03 output[0]
+ None output[1]
+2.25e-01 1.00e+04 output[2]
+ encoder.block.2.layer.1.layer_norm T5LayerNorm
+8.69e-02 4.18e-01 weight
+2.65e-04 3.42e+03 input[0]
+1.79e-06 4.65e+00 output
+ encoder.block.2.layer.1.DenseReluDense.wi_0 Linear
+2.17e-07 4.50e+00 weight
+1.79e-06 4.65e+00 input[0]
+2.68e-06 3.70e+01 output
+ encoder.block.2.layer.1.DenseReluDense.wi_1 Linear
+8.08e-07 2.66e+01 weight
+1.79e-06 4.65e+00 input[0]
+1.27e-04 2.37e+02 output
+ encoder.block.2.layer.1.DenseReluDense.dropout Dropout
+0.00e+00 8.76e+03 input[0]
+0.00e+00 9.74e+03 output
+ encoder.block.2.layer.1.DenseReluDense.wo Linear
+1.01e-06 6.44e+00 weight
+0.00e+00 9.74e+03 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.DenseReluDense T5DenseGatedGeluDense
+1.79e-06 4.65e+00 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.dropout Dropout
+3.18e-04 6.27e+04 input[0]
+0.00e+00 inf output
+```
+
+El output del ejemplo se ha recortado en el centro por razones de brevedad.
+
+La segunda columna muestra el valor del elemento más grande en términos absolutos, por lo que si observas con detenimiento los últimos fotogramas,
+los inputs y outputs estaban en el rango de `1e4`. Así que cuando este entrenamiento se hizo con fp16 mixed precision,
+el último paso sufrió overflow (ya que bajo `fp16` el mayor número antes de `inf` es `64e3`). Para evitar overflows en
+`fp16` las activations deben permanecer muy por debajo de `1e4`, porque `1e4 * 1e4 = 1e8` por lo que cualquier matrix multiplication con
+grandes activations va a llevar a una condición de overflow numérico.
+
+Al principio del output puedes descubrir en qué número de batch se produjo el problema (aquí `Detected inf/nan during batch_number=0` significa que el problema se produjo en el primer batch).
+
+Cada frame del informe comienza declarando la entrada completamente calificada para el módulo correspondiente que este frame está reportando.
+Si nos fijamos sólo en este frame:
+
+```
+ encoder.block.2.layer.1.layer_norm T5LayerNorm
+8.69e-02 4.18e-01 weight
+2.65e-04 3.42e+03 input[0]
+1.79e-06 4.65e+00 output
+```
+
+Aquí, `encoder.block.2.layer.1.layer_norm` indica que era una layer norm para la primera capa, del segundo
+block del encoder. Y la call específica del `forward` es `T5LayerNorm`.
+
+Veamos los últimos frames de ese informe:
+
+```
+Detected inf/nan during batch_number=0
+Last 21 forward frames:
+abs min abs max metadata
+[...]
+ encoder.block.2.layer.1.DenseReluDense.wi_0 Linear
+2.17e-07 4.50e+00 weight
+1.79e-06 4.65e+00 input[0]
+2.68e-06 3.70e+01 output
+ encoder.block.2.layer.1.DenseReluDense.wi_1 Linear
+8.08e-07 2.66e+01 weight
+1.79e-06 4.65e+00 input[0]
+1.27e-04 2.37e+02 output
+ encoder.block.2.layer.1.DenseReluDense.wo Linear
+1.01e-06 6.44e+00 weight
+0.00e+00 9.74e+03 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.DenseReluDense T5DenseGatedGeluDense
+1.79e-06 4.65e+00 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.dropout Dropout
+3.18e-04 6.27e+04 input[0]
+0.00e+00 inf output
+```
+
+El último frame informa para la función `Dropout.forward` con la primera entrada para el único input y la segunda para el
+único output. Puedes ver que fue llamada desde un atributo `dropout` dentro de la clase `DenseReluDense`. Podemos ver
+que ocurrió durante la primera capa, del segundo block, durante el primer batch. Por último, el mayor absoluto
+elementos de input fue `6.27e+04` y el mismo para el output fue `inf`.
+
+Puedes ver aquí, que `T5DenseGatedGeluDense.forward` resultó en output activations, cuyo valor máximo absoluto fue
+alrededor de 62.7K, que está muy cerca del límite máximo de fp16 de 64K. En el siguiente frame tenemos `Dropout`, el cual renormaliza
+los weights, después de poner a cero algunos de los elementos, lo que empuja el valor máximo absoluto a más de 64K, y obtenemos un
+overflow (`inf`).
+
+Como puedes ver son los frames anteriores los que tenemos que mirar cuando los números empiezan a ser muy grandes para números fp16.
+
+Combinemos el informe con el código de `models/t5/modeling_t5.py`:
+
+```python
+class T5DenseGatedGeluDense(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.wi_0 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wi_1 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wo = nn.Linear(config.d_ff, config.d_model, bias=False)
+ self.dropout = nn.Dropout(config.dropout_rate)
+ self.gelu_act = ACT2FN["gelu_new"]
+
+ def forward(self, hidden_states):
+ hidden_gelu = self.gelu_act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+```
+
+Ahora es fácil ver la call `dropout`, y también todas las calls anteriores.
+
+Dado que la detección se produce en un forward hook, estos informes se imprimen inmediatamente después de que cada `forward`
+responda.
+
+Volviendo al informe completo, para actuar sobre él y arreglar el problema, tenemos que subir unos cuantos frames donde los números
+empezaron a subir y probablemente cambiar al modo `fp32` aquí, para que los números no sufran overflow cuando se multipliquen
+o al sumarlos. Por supuesto, puede haber otras soluciones. Por ejemplo, podríamos desactivar `amp` temporalmente si está
+activado, después de mover el original `forward` dentro de un helper wrapper, así:
+
+```python
+def _forward(self, hidden_states):
+ hidden_gelu = self.gelu_act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+import torch
+
+
+def forward(self, hidden_states):
+ if torch.is_autocast_enabled():
+ with torch.cuda.amp.autocast(enabled=False):
+ return self._forward(hidden_states)
+ else:
+ return self._forward(hidden_states)
+```
+
+Como el detector automático sólo informa de los inputs y outputs de los frames completos, una vez que sepas dónde buscar, puedes
+analizar también las etapas intermedias de una función específica de `forward`. En este caso, puede utilizar la función
+función de ayuda `detect_overflow` para inyectar el detector donde quieras, por ejemplo:
+
+```python
+from debug_utils import detect_overflow
+
+
+class T5LayerFF(nn.Module):
+ [...]
+
+ def forward(self, hidden_states):
+ forwarded_states = self.layer_norm(hidden_states)
+ detect_overflow(forwarded_states, "after layer_norm")
+ forwarded_states = self.DenseReluDense(forwarded_states)
+ detect_overflow(forwarded_states, "after DenseReluDense")
+ return hidden_states + self.dropout(forwarded_states)
+```
+
+Puedes ver que hemos añadido 2 de estos y ahora se trackea si `inf` o `nan` para `forwarded_states` fue detectado
+en algún punto intermedio.
+
+De hecho, el detector ya informa de esto porque cada una de las llamadas en el ejemplo anterior es un `nn.Module`, pero
+digamos que si tuvieras algunos cálculos directos locales, así es como lo harías.
+
+Además, si estás instanciando el debugger en tu propio código, puedes ajustar el número de frames impresos de
+su valor por defecto, por ejemplo:
+
+```python
+from .debug_utils import DebugUnderflowOverflow
+
+debug_overflow = DebugUnderflowOverflow(model, max_frames_to_save=100)
+```
+
+### Rastreo de valores mínimos y máximos absolutos de batches específicos
+
+La misma clase de debugging se puede utilizar para el rastreo por batches con la función de detección de underflow/overflow desactivada.
+
+Digamos que quieres ver los valores mínimos y máximos absolutos de todos los ingredientes de cada call `forward` de un determinado
+batch, y sólo hacerlo para los batches 1 y 3. Entonces instancias esta clase como:
+
+```python
+debug_overflow = DebugUnderflowOverflow(model, trace_batch_nums=[1, 3])
+```
+
+Y ahora los batches 1 y 3 completos serán rastreados usando el mismo formato que el detector de underflow/overflow.
+
+Los batches son 0-index.
+
+Esto es muy útil si sabes que el programa empieza a comportarse mal después de un determinado número de batch, para que puedas avanzar rápidamente
+hasta esa área. Aquí hay un ejemplo de output recortado para tal configuración:
+
+```
+ *** Starting batch number=1 ***
+abs min abs max metadata
+ shared Embedding
+1.01e-06 7.92e+02 weight
+0.00e+00 2.47e+04 input[0]
+5.36e-05 7.92e+02 output
+[...]
+ decoder.dropout Dropout
+1.60e-07 2.27e+01 input[0]
+0.00e+00 2.52e+01 output
+ decoder T5Stack
+ not a tensor output
+ lm_head Linear
+1.01e-06 7.92e+02 weight
+0.00e+00 1.11e+00 input[0]
+6.06e-02 8.39e+01 output
+ T5ForConditionalGeneration
+ not a tensor output
+
+ *** Starting batch number=3 ***
+abs min abs max metadata
+ shared Embedding
+1.01e-06 7.92e+02 weight
+0.00e+00 2.78e+04 input[0]
+5.36e-05 7.92e+02 output
+[...]
+```
+
+Aquí obtendrás un gran número de frames mostrados - tantos como forward calls haya en tu modelo, por lo que puede o no ser lo que quieras, pero a veces puede ser más fácil de usar para debug que un debugger normal.
+Por ejemplo, si un problema comienza a ocurrir en el batch 150. Entonces puedes mostrar las trazas de los batches 149 y 150 y comparar dónde
+los números empezaron a divergir.
+
+También puedes especificar el número de batch después del cual se debe detener el entrenamiento, con:
+
+```python
+debug_overflow = DebugUnderflowOverflow(model, trace_batch_nums=[1, 3], abort_after_batch_num=3)
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/fast_tokenizers.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/fast_tokenizers.md
new file mode 100644
index 0000000000000000000000000000000000000000..92b925f67f7e47b604ba1e0efd7bae23324a4313
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/fast_tokenizers.md
@@ -0,0 +1,74 @@
+
+
+# Usa los tokenizadores de 🤗 Tokenizers
+
+[`PreTrainedTokenizerFast`] depende de la biblioteca [🤗 Tokenizers](https://huggingface.co/docs/tokenizers). Los tokenizadores obtenidos desde la biblioteca 🤗 Tokenizers pueden ser
+cargados de forma muy sencilla en los 🤗 Transformers.
+
+Antes de entrar en detalles, comencemos creando un tokenizador dummy en unas cuantas líneas:
+
+```python
+>>> from tokenizers import Tokenizer
+>>> from tokenizers.models import BPE
+>>> from tokenizers.trainers import BpeTrainer
+>>> from tokenizers.pre_tokenizers import Whitespace
+
+>>> tokenizer = Tokenizer(BPE(unk_token="[UNK]"))
+>>> trainer = BpeTrainer(special_tokens=["[UNK]", "[CLS]", "[SEP]", "[PAD]", "[MASK]"])
+
+>>> tokenizer.pre_tokenizer = Whitespace()
+>>> files = [...]
+>>> tokenizer.train(files, trainer)
+```
+
+Ahora tenemos un tokenizador entrenado en los archivos que definimos. Lo podemos seguir utilizando en ese entorno de ejecución (runtime en inglés), o puedes guardarlo
+en un archivo JSON para reutilizarlo en un futuro.
+
+## Cargando directamente desde el objeto tokenizador
+
+Veamos cómo utilizar este objeto tokenizador en la biblioteca 🤗 Transformers. La clase
+[`PreTrainedTokenizerFast`] permite una instanciación fácil, al aceptar el objeto
+*tokenizer* instanciado como argumento:
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_object=tokenizer)
+```
+
+Este objeto ya puede ser utilizado con todos los métodos compartidos por los tokenizadores de 🤗 Transformers! Visita la [página sobre tokenizadores
+](main_classes/tokenizer) para más información.
+
+## Cargando desde un archivo JSON
+
+Para cargar un tokenizador desde un archivo JSON, comencemos por guardar nuestro tokenizador:
+
+```python
+>>> tokenizer.save("tokenizer.json")
+```
+
+La localización (path en inglés) donde este archivo es guardado puede ser incluida en el método de inicialización de [`PreTrainedTokenizerFast`]
+utilizando el parámetro `tokenizer_file`:
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_file="tokenizer.json")
+```
+
+Este objeto ya puede ser utilizado con todos los métodos compartidos por los tokenizadores de 🤗 Transformers! Visita la [página sobre tokenizadores
+](main_classes/tokenizer) para más información.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/glossary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/glossary.md
new file mode 100644
index 0000000000000000000000000000000000000000..790fa1fecbe69a0fcd989d431462d539c4883383
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/glossary.md
@@ -0,0 +1,464 @@
+
+
+# Glosario
+
+Este glosario define términos generales de aprendizaje automático y términos relacionados con 🤗 Transformers para ayudarte a comprender mejor la documentación.
+
+## A
+
+### attention mask
+
+La máscara de atención es un argumento opcional utilizado al agrupar secuencias.
+
+
+
+Las etiquetas de cada modelo pueden ser diferentes, así que asegúrate siempre de revisar la documentación de cada modelo para obtener más información sobre sus etiquetas específicas.
+
+
+
+Los modelos base ([`BertModel`]) no aceptan etiquetas, ya que estos son los modelos base de transformadores, que simplemente generan características.
+
+### large language models (LLM)
+
+Un término genérico que se refiere a modelos de lenguaje de transformadores (GPT-3, BLOOM, OPT) que fueron entrenados con una gran cantidad de datos. Estos modelos también tienden a tener un gran número de parámetros que se pueden aprender (por ejemplo, 175 mil millones para GPT-3).
+
+## M
+
+### masked language modeling (MLM)
+
+Una tarea de preentrenamiento en la que el modelo ve una versión corrupta de los textos, generalmente hecha
+al enmascarar algunos tokens al azar, y tiene que predecir el texto original.
+
+### multimodal
+
+Una tarea que combina textos con otro tipo de entradas (por ejemplo: imágenes).
+
+## N
+
+### Natural language generation (NLG)
+
+Todas las tareas relacionadas con la generación de texto (por ejemplo: [Escribe con Transformers](https://transformer.huggingface.co/) o traducción).
+
+### Natural language processing (NLP)
+
+Una forma genérica de decir "trabajar con textos".
+
+### Natural language understanding (NLU)
+
+Todas las tareas relacionadas con entender lo que hay en un texto (por ejemplo: clasificar el
+texto completo o palabras individuales).
+
+## P
+
+### Pipeline
+
+Un pipeline en 🤗 Transformers es una abstracción que se refiere a una serie de pasos que se ejecutan en un orden específico para preprocesar y transformar datos y devolver una predicción de un modelo. Algunas etapas de ejemplo que se encuentran en un pipeline pueden ser el preprocesamiento de datos, la extracción de características y la normalización.
+
+Para obtener más detalles, consulta [Pipelines para inferencia](https://huggingface.co/docs/transformers/pipeline_tutorial).
+
+### PipelineParallel (PP)
+
+Técnica de paralelismo en la que el modelo se divide verticalmente (a nivel de capa) en varios GPU, de modo que solo una o varias capas del modelo se colocan en un solo GPU. Cada GPU procesa en paralelo diferentes etapas del pipeline y trabaja en un pequeño fragmento del lote. Obtén más información sobre cómo funciona PipelineParallel [aquí](perf_train_gpu_many#from-naive-model-parallelism-to-pipeline-parallelism).
+
+### pixel values
+
+Un tensor de las representaciones numéricas de una imagen que se pasa a un modelo. Los valores de píxeles tienen una forma de [`batch_size`, `num_channels`, `height`, `width`], y se generan a partir de un procesador de imágenes.
+
+### pooling
+
+Una operación que reduce una matriz a una matriz más pequeña, ya sea tomando el máximo o el promedio de la dimensión (o dimensiones) agrupada(s). Las capas de agrupación se encuentran comúnmente entre capas convolucionales para reducir la representación de características.
+
+### position IDs
+
+A diferencia de las RNN que tienen la posición de cada token incrustada en ellas, los transformers no son conscientes de la posición de cada token. Por lo tanto, se utilizan los IDs de posición (`position_ids`) para que el modelo identifique la posición de cada token en la lista de tokens.
+
+Son un parámetro opcional. Si no se pasan `position_ids` al modelo, los IDs se crean automáticamente como embeddings de posición absolutas.
+
+Los embeddings de posición absolutas se seleccionan en el rango `[0, config.max_position_embeddings - 1]`. Algunos modelos utilizan otros tipos de embeddings de posición, como embeddings de posición sinusoidales o embeddings de posición relativas.
+
+### preprocessing
+
+La tarea de preparar datos crudos en un formato que pueda ser fácilmente consumido por modelos de aprendizaje automático. Por ejemplo, el texto se preprocesa típicamente mediante la tokenización. Para tener una mejor idea de cómo es el preprocesamiento para otros tipos de entrada, consulta el tutorial [Pre-procesar](https://huggingface.co/docs/transformers/preprocessing).
+
+### pretrained model
+
+Un modelo que ha sido pre-entrenado en algunos datos (por ejemplo, toda Wikipedia). Los métodos de preentrenamiento involucran un objetivo auto-supervisado, que puede ser leer el texto e intentar predecir la siguiente palabra (ver [modelado de lenguaje causal](#causal-language-modeling)) o enmascarar algunas palabras e intentar predecirlas (ver [modelado de lenguaje enmascarado](#masked-language-modeling-mlm)).
+
+Los modelos de habla y visión tienen sus propios objetivos de pre-entrenamiento. Por ejemplo, Wav2Vec2 es un modelo de habla pre-entrenado en una tarea contrastiva que requiere que el modelo identifique la representación de habla "verdadera" de un conjunto de representaciones de habla "falsas". Por otro lado, BEiT es un modelo de visión pre-entrenado en una tarea de modelado de imágenes enmascaradas que enmascara algunos de los parches de la imagen y requiere que el modelo prediga los parches enmascarados (similar al objetivo de modelado de lenguaje enmascarado).
+
+## R
+
+### recurrent neural network (RNN)
+
+Un tipo de modelo que utiliza un bucle sobre una capa para procesar textos.
+
+### representation learning
+
+Un subcampo del aprendizaje automático que se centra en aprender representaciones significativas de datos en bruto. Algunos ejemplos de técnicas de aprendizaje de representaciones incluyen embeddings de palabras, auto-encoders y Redes Generativas Adversarias (Generative Adversarial Networks, GANs).
+
+## S
+
+### sampling rate
+
+Una medida en hercios del número de muestras (la señal de audio) tomadas por segundo. La tasa de muestreo es el resultado de aproximar una señal continua como el habla.
+
+### self-attention
+
+Cada elemento de la entrada averigua a cuáles otros elementos de la entrada debe prestar atención.
+
+### self-supervised learning
+
+Una categoría de técnicas de aprendizaje automático en la que un modelo crea su propio objetivo de aprendizaje a partir de datos no etiquetados. Difiere del [aprendizaje no supervisado](#unsupervised-learning) y del [aprendizaje supervisado](#supervised-learning) en que el proceso de aprendizaje está supervisado, pero no explícitamente por el usuario.
+
+Un ejemplo de aprendizaje auto-supervisado es el [modelado de lenguaje enmascarado](#masked-language-modeling-mlm), donde un modelo recibe oraciones con una proporción de sus tokens eliminados y aprende a predecir los tokens faltantes.
+
+### semi-supervised learning
+
+Una amplia categoría de técnicas de entrenamiento de aprendizaje automático que aprovecha una pequeña cantidad de datos etiquetados con una mayor cantidad de datos no etiquetados para mejorar la precisión de un modelo, a diferencia del [aprendizaje supervisado](#supervised-learning) y del [aprendizaje no supervisado](#unsupervised-learning).
+
+Un ejemplo de un enfoque de aprendizaje semi-supervisado es "auto-entrenamiento", en el que un modelo se entrena con datos etiquetados y luego se utiliza para hacer predicciones sobre los datos no etiquetados. La porción de datos no etiquetados que el modelo predice con mayor confianza se agrega al conjunto de datos etiquetados y se utiliza para volver a entrenar el modelo.
+
+### sequence-to-sequence (seq2seq)
+
+Modelos que generan una nueva secuencia a partir de una entrada, como modelos de traducción o modelos de resumen (como
+[Bart](model_doc/bart) o [T5](model_doc/t5)).
+
+### Sharded DDP
+
+Otro nombre para el concepto fundamental de [ZeRO](#zero-redundancy-optimizer-zero) utilizado por varias otras implementaciones de ZeRO.
+
+### stride
+
+En [convolución](#convolution) o [agrupación](#pooling), el paso (stride) se refiere a la distancia que recorre el núcleo sobre una matriz. Un paso de 1 significa que el núcleo se mueve un píxel a la vez, y un paso de 2 significa que el núcleo se mueve dos píxeles a la vez.
+
+### supervised learning
+
+Una forma de entrenamiento de modelos que utiliza directamente datos etiquetados para corregir y dirigir el rendimiento del modelo. Los datos se introducen en el modelo en entrenamiento, y sus predicciones se comparan con las etiquetas conocidas. El modelo actualiza sus pesos en función de cuán incorrectas fueron sus predicciones, y el proceso se repite para optimizar el rendimiento del modelo.
+
+## T
+
+### Tensor Parallelism (TP)
+
+Técnica de paralelismo para entrenamiento en múltiples GPU en la que cada tensor se divide en múltiples fragmentos, de modo que en lugar de tener todo el tensor en una sola GPU, cada fragmento del tensor reside en su GPU designada. Los fragmentos se procesan por separado y en paralelo en diferentes GPU y los resultados se sincronizan al final del paso de procesamiento.Esto es lo que a veces se llama paralelismo horizontal, ya que la división ocurre a nivel horizontal.
+Obtén más información sobre el Paralelismo de Tensores [aquí](perf_train_gpu_many#tensor-parallelism).
+
+### token
+
+Parte de una oración, generalmente una palabra, pero también puede ser una sub-palabra (las palabras no comunes a menudo se dividen en sub-palabras) o un símbolo de puntuación.
+
+### token Type IDs
+
+Algunos modelos tienen como objetivo realizar clasificación en pares de oraciones o responder preguntas.
+
+
+
+
+## Contenidos
+
+La documentación está organizada en cuatro partes:
+
+- **EMPEZAR** contiene un recorrido rápido e instrucciones de instalación para comenzar a usar 🤗 Transformers.
+- **TUTORIALES** es un excelente lugar para comenzar. Esta sección te ayudará a obtener las habilidades básicas que necesitas para comenzar a usar 🤗 Transformers.
+- **GUÍAS PRÁCTICAS** te mostrará cómo lograr un objetivo específico, cómo hacer fine-tuning a un modelo preentrenado para el modelado de lenguaje o cómo crear un cabezal para un modelo personalizado.
+- **GUÍAS CONCEPTUALES** proporciona más discusión y explicación de los conceptos e ideas subyacentes detrás de los modelos, las tareas y la filosofía de diseño de 🤗 Transformers.
+
+La biblioteca actualmente contiene implementaciones de JAX, PyTorch y TensorFlow, pesos de modelos preentrenados, scripts de uso y utilidades de conversión para los siguientes modelos.
+
+### Modelos compatibles
+
+
+
+1. **[ALBERT](model_doc/albert)** (de Google Research y el Instituto Tecnológico de Toyota en Chicago) publicado con el paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942), por Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
+1. **[ALIGN](model_doc/align)** (de Google Research) publicado con el paper [Scaling Up Visual and Vision-Language Representation Learning With Noisy Text Supervision](https://arxiv.org/abs/2102.05918) por Chao Jia, Yinfei Yang, Ye Xia, Yi-Ting Chen, Zarana Parekh, Hieu Pham, Quoc V. Le, Yunhsuan Sung, Zhen Li, Tom Duerig.
+1. **[BART](model_doc/bart)** (de Facebook) publicado con el paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461) por Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov y Luke Zettlemoyer.
+1. **[BARThez](model_doc/barthez)** (de École polytechnique) publicado con el paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321) por Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
+1. **[BARTpho](model_doc/bartpho)** (de VinAI Research) publicado con el paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701) por Nguyen Luong Tran, Duong Minh Le y Dat Quoc Nguyen.
+1. **[BEiT](model_doc/beit)** (de Microsoft) publicado con el paper [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) por Hangbo Bao, Li Dong, Furu Wei.
+1. **[BERT](model_doc/bert)** (de Google) publicado con el paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) por Jacob Devlin, Ming-Wei Chang, Kenton Lee y Kristina Toutanova.
+1. **[BERTweet](model_doc/bertweet)** (de VinAI Research) publicado con el paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) por Dat Quoc Nguyen, Thanh Vu y Anh Tuan Nguyen.
+1. **[BERT For Sequence Generation](model_doc/bert-generation)** (de Google) publicado con el paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) por Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[BigBird-RoBERTa](model_doc/big_bird)** (de Google Research) publicado con el paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) por Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (de Google Research) publicado con el paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) por Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[Blenderbot](model_doc/blenderbot)** (de Facebook) publicado con el paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) por Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BlenderbotSmall](model_doc/blenderbot-small)** (de Facebook) publicado con el paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) por Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BORT](model_doc/bort)** (de Alexa) publicado con el paper [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499) por Adrian de Wynter y Daniel J. Perry.
+1. **[ByT5](model_doc/byt5)** (de Google Research) publicado con el paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) por Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
+1. **[CamemBERT](model_doc/camembert)** (de Inria/Facebook/Sorbonne) publicado con el paper [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) por Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah y Benoît Sagot.
+1. **[CANINE](model_doc/canine)** (de Google Research) publicado con el paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874) por Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
+1. **[ConvNeXT](model_doc/convnext)** (de Facebook AI) publicado con el paper [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) por Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+1. **[ConvNeXTV2](model_doc/convnextv2)** (de Facebook AI) publicado con el paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) por Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CLIP](model_doc/clip)** (de OpenAI) publicado con el paper [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) por Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
+1. **[ConvBERT](model_doc/convbert)** (de YituTech) publicado con el paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) por Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
+1. **[CPM](model_doc/cpm)** (de Universidad de Tsinghua) publicado con el paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413) por Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+1. **[CTRL](model_doc/ctrl)** (de Salesforce) publicado con el paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) por Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong y Richard Socher.
+1. **[Data2Vec](model_doc/data2vec)** (de Facebook) publicado con el paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555) por Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
+1. **[DeBERTa](model_doc/deberta)** (de Microsoft) publicado con el paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) por Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[DeBERTa-v2](model_doc/deberta-v2)** (de Microsoft) publicado con el paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) por Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[Decision Transformer](model_doc/decision_transformer)** (de Berkeley/Facebook/Google) publicado con el paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) por Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+1. **[DiT](model_doc/dit)** (de Microsoft Research) publicado con el paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378) por Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
+1. **[DeiT](model_doc/deit)** (de Facebook) publicado con el paper [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877) por Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
+1. **[DETR](model_doc/detr)** (de Facebook) publicado con el paper [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872) por Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
+1. **[DialoGPT](model_doc/dialogpt)** (de Microsoft Research) publicado con el paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536) por Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
+1. **[DistilBERT](model_doc/distilbert)** (de HuggingFace), publicado junto con el paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108) por Victor Sanh, Lysandre Debut y Thomas Wolf. Se ha aplicado el mismo método para comprimir GPT2 en [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), RoBERTa en [DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), BERT multilingüe en [DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) y una versión alemana de DistilBERT.
+1. **[DPR](model_doc/dpr)** (de Facebook) publicado con el paper [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906) por Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, y Wen-tau Yih.
+1. **[DPT](master/model_doc/dpt)** (de Intel Labs) publicado con el paper [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413) por René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+1. **[EfficientNet](model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://arxiv.org/abs/1905.11946) by Mingxing Tan and Quoc V. Le.
+1. **[EncoderDecoder](model_doc/encoder-decoder)** (de Google Research) publicado con el paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) por Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[ELECTRA](model_doc/electra)** (de Google Research/Universidad de Stanford) publicado con el paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555) por Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
+1. **[FlauBERT](model_doc/flaubert)** (de CNRS) publicado con el paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) por Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
+1. **[FNet](model_doc/fnet)** (de Google Research) publicado con el paper [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) por James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
+1. **[Funnel Transformer](model_doc/funnel)** (de CMU/Google Brain) publicado con el paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236) por Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
+1. **[GLPN](model_doc/glpn)** (de KAIST) publicado con el paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) por Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+1. **[GPT](model_doc/openai-gpt)** (de OpenAI) publicado con el paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) por Alec Radford, Karthik Narasimhan, Tim Salimans y Ilya Sutskever.
+1. **[GPT-2](model_doc/gpt2)** (de OpenAI) publicado con el paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) por Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei y Ilya Sutskever.
+1. **[GPT-J](model_doc/gptj)** (de EleutherAI) publicado con el repositorio [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) por Ben Wang y Aran Komatsuzaki.
+1. **[GPT Neo](model_doc/gpt_neo)** (de EleutherAI) publicado en el paper [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) por Sid Black, Stella Biderman, Leo Gao, Phil Wang y Connor Leahy.
+1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released with [GPTSAN](https://github.com/tanreinama/GPTSAN) by Toshiyuki Sakamoto (tanreinama).
+1. **[Hubert](model_doc/hubert)** (de Facebook) publicado con el paper [HuBERT: Self-Supervised Speech Representation Learning por Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) por Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
+1. **[I-BERT](model_doc/ibert)** (de Berkeley) publicado con el paper [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) por Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
+1. **[ImageGPT](model_doc/imagegpt)** (de OpenAI) publicado con el paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) por Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
+1. **[LayoutLM](model_doc/layoutlm)** (de Microsoft Research Asia) publicado con el paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318) por Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
+1. **[LayoutLMv2](model_doc/layoutlmv2)** (de Microsoft Research Asia) publicado con el paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) por Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
+1. **[LayoutXLM](model_doc/layoutxlm)** (de Microsoft Research Asia) publicado con el paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) por Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
+1. **[LED](model_doc/led)** (de AllenAI) publicado con el paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) por Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[Longformer](model_doc/longformer)** (de AllenAI) publicado con el paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) por Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LUKE](model_doc/luke)** (de Studio Ousia) publicado con el paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) por Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
+1. **[mLUKE](model_doc/mluke)** (de Studio Ousia) publicado con el paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) por Ryokan Ri, Ikuya Yamada, y Yoshimasa Tsuruoka.
+1. **[LXMERT](model_doc/lxmert)** (de UNC Chapel Hill) publicado con el paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490) por Hao Tan y Mohit Bansal.
+1. **[M2M100](model_doc/m2m_100)** (de Facebook) publicado con el paper [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) por Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+1. **[MarianMT](model_doc/marian)** Modelos de traducción automática entrenados usando [OPUS](http://opus.nlpl.eu/) data por Jörg Tiedemann. El [Marian Framework](https://marian-nmt.github.io/) está siendo desarrollado por el equipo de traductores de Microsoft.
+1. **[Mask2Former](model_doc/mask2former)** (de FAIR y UIUC) publicado con el paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) por Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
+1. **[MaskFormer](model_doc/maskformer)** (de Meta y UIUC) publicado con el paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) por Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
+1. **[MBart](model_doc/mbart)** (de Facebook) publicado con el paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) por Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+1. **[MBart-50](model_doc/mbart)** (de Facebook) publicado con el paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) por Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
+1. **[Megatron-BERT](model_doc/megatron-bert)** (de NVIDIA) publicado con el paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) por Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper y Bryan Catanzaro.
+1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (de NVIDIA) publicado con el paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) por Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper y Bryan Catanzaro.
+1. **[MPNet](model_doc/mpnet)** (de Microsoft Research) publicado con el paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) por Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+1. **[MT5](model_doc/mt5)** (de Google AI) publicado con el paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) por Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
+1. **[Nyströmformer](model_doc/nystromformer)** (de la Universidad de Wisconsin - Madison) publicado con el paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902) por Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
+1. **[OneFormer](model_doc/oneformer)** (de la SHI Labs) publicado con el paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) por Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
+1. **[Pegasus](model_doc/pegasus)** (de Google) publicado con el paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777) por Jingqing Zhang, Yao Zhao, Mohammad Saleh y Peter J. Liu.
+1. **[Perceiver IO](model_doc/perceiver)** (de Deepmind) publicado con el paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795) por Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+1. **[PhoBERT](model_doc/phobert)** (de VinAI Research) publicado con el paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) por Dat Quoc Nguyen y Anh Tuan Nguyen.
+1. **[PLBart](model_doc/plbart)** (de UCLA NLP) publicado con el paper [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) por Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+1. **[PoolFormer](model_doc/poolformer)** (de Sea AI Labs) publicado con el paper [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) por Yu, Weihao y Luo, Mi y Zhou, Pan y Si, Chenyang y Zhou, Yichen y Wang, Xinchao y Feng, Jiashi y Yan, Shuicheng.
+1. **[ProphetNet](model_doc/prophetnet)** (de Microsoft Research) publicado con el paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) por Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang y Ming Zhou.
+1. **[QDQBert](model_doc/qdqbert)** (de NVIDIA) publicado con el paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602) por Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev y Paulius Micikevicius.
+1. **[REALM](model_doc/realm.html)** (de Google Research) publicado con el paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) por Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat y Ming-Wei Chang.
+1. **[Reformer](model_doc/reformer)** (de Google Research) publicado con el paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451) por Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+1. **[RemBERT](model_doc/rembert)** (de Google Research) publicado con el paper [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821) por Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
+1. **[RegNet](model_doc/regnet)** (de META Platforms) publicado con el paper [Designing Network Design Space](https://arxiv.org/abs/2003.13678) por Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+1. **[ResNet](model_doc/resnet)** (de Microsoft Research) publicado con el paper [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) por Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
+1. **[RoBERTa](model_doc/roberta)** (de Facebook), publicado junto con el paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) por Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
+1. **[RoFormer](model_doc/roformer)** (de ZhuiyiTechnology), publicado junto con el paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864) por Jianlin Su y Yu Lu y Shengfeng Pan y Bo Wen y Yunfeng Liu.
+1. **[SegFormer](model_doc/segformer)** (de NVIDIA) publicado con el paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) por Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
+1. **[SEW](model_doc/sew)** (de ASAPP) publicado con el paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) por Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SEW-D](model_doc/sew_d)** (de ASAPP) publicado con el paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) por Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (de Facebook), publicado junto con el paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) por Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
+1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (de Facebook), publicado junto con el paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) por Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+1. **[Splinter](model_doc/splinter)** (de Universidad de Tel Aviv), publicado junto con el paper [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) pory Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
+1. **[SqueezeBert](model_doc/squeezebert)** (de Berkeley) publicado con el paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) por Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, y Kurt W. Keutzer.
+1. **[Swin Transformer](model_doc/swin)** (de Microsoft) publicado con el paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030) por Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+1. **[T5](model_doc/t5)** (de Google AI) publicado con el paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) por Colin Raffel y Noam Shazeer y Adam Roberts y Katherine Lee y Sharan Narang y Michael Matena y Yanqi Zhou y Wei Li y Peter J. Liu.
+1. **[T5v1.1](model_doc/t5v1.1)** (de Google AI) publicado en el repositorio [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) por Colin Raffel y Noam Shazeer y Adam Roberts y Katherine Lee y Sharan Narang y Michael Matena y Yanqi Zhou y Wei Li y Peter J. Liu.
+1. **[TAPAS](model_doc/tapas)** (de Google AI) publicado con el paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349) por Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno y Julian Martin Eisenschlos.
+1. **[TAPEX](model_doc/tapex)** (de Microsoft Research) publicado con el paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) por Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
+1. **[Transformer-XL](model_doc/transfo-xl)** (de Google/CMU) publicado con el paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) por Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
+1. **[TrOCR](model_doc/trocr)** (de Microsoft), publicado junto con el paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) por Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
+1. **[UniSpeech](model_doc/unispeech)** (de Microsoft Research) publicado con el paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) por Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
+1. **[UniSpeechSat](model_doc/unispeech-sat)** (de Microsoft Research) publicado con el paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752) por Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
+1. **[VAN](model_doc/van)** (de la Universidad de Tsinghua y la Universidad de Nankai) publicado con el paper [Visual Attention Network](https://arxiv.org/abs/2202.09741) por Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+1. **[ViLT](model_doc/vilt)** (de NAVER AI Lab/Kakao Enterprise/Kakao Brain) publicado con el paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334) por Wonjae Kim, Bokyung Son, Ildoo Kim.
+1. **[Vision Transformer (ViT)](model_doc/vit)** (de Google AI) publicado con el paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) por Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[ViTMAE](model_doc/vit_mae)** (de Meta AI) publicado con el paper [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377) por Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
+1. **[VisualBERT](model_doc/visual_bert)** (de UCLA NLP) publicado con el paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557) por Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
+1. **[WavLM](model_doc/wavlm)** (de Microsoft Research) publicado con el paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900) por Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
+1. **[Wav2Vec2](model_doc/wav2vec2)** (de Facebook AI) publicado con el paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477) por Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
+1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (de Facebook AI) publicado con el paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680) por Qiantong Xu, Alexei Baevski, Michael Auli.
+1. **[XGLM](model_doc/xglm)** (de Facebook AI) publicado con el paper [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668) por Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
+1. **[XLM](model_doc/xlm)** (de Facebook) publicado junto con el paper [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291) por Guillaume Lample y Alexis Conneau.
+1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (de Microsoft Research) publicado con el paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) por Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang y Ming Zhou.
+1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (de Facebook AI), publicado junto con el paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) por Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer y Veselin Stoyanov.
+1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (de Facebook AI), publicado junto con el paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572) por Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
+1. **[XLNet](model_doc/xlnet)** (de Google/CMU) publicado con el paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237) por Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
+1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (de Facebook AI) publicado con el paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979) por Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
+1. **[XLS-R](model_doc/xls_r)** (de Facebook AI) publicado con el paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296) por Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
+1. **[YOSO](model_doc/yoso)** (de la Universidad de Wisconsin-Madison) publicado con el paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714) por Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
+
+
+### Frameworks compatibles
+
+La siguiente tabla representa el soporte actual en la biblioteca para cada uno de esos modelos, ya sea que tengan un tokenizador de Python (llamado "slow"). Un tokenizador "fast" respaldado por la biblioteca 🤗 Tokenizers, ya sea que tengan soporte en Jax (a través de
+Flax), PyTorch y/o TensorFlow.
+
+
+
+| Modelo | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:---------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBirdPegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Canine | ✅ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNext | ❌ | ❌ | ✅ | ✅ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MegatronBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| mT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Nystromformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Realm | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ❌ | ✅ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| SegFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Swin | ❌ | ❌ | ✅ | ❌ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TAPEX | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| VisualBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ❌ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLMProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/installation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/installation.md
new file mode 100644
index 0000000000000000000000000000000000000000..714c3b195ebcc09d052f11ce9c34d4f301c54f02
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/installation.md
@@ -0,0 +1,242 @@
+
+
+# Instalación
+
+En esta guía puedes encontrar información para instalar 🤗 Transformers para cualquier biblioteca de Machine Learning con la que estés trabajando. Además, encontrarás información sobre cómo establecer el caché y cómo configurar 🤗 Transformers para correrlo de manera offline (opcional).
+
+🤗 Transformers ha sido probada en Python 3.6+, PyTorch 1.1.0+, TensorFlow 2.0+, y Flax. Para instalar la biblioteca de deep learning con la que desees trabajar, sigue las instrucciones correspondientes listadas a continuación:
+
+* [PyTorch](https://pytorch.org/get-started/locally/)
+* [TensorFlow 2.0](https://www.tensorflow.org/install/pip)
+* [Flax](https://flax.readthedocs.io/en/latest/)
+
+## Instalación con pip
+
+Es necesario instalar 🤗 Transformers en un [entorno virtual](https://docs.python.org/3/library/venv.html). Si necesitas más información sobre entornos virtuales de Python, consulta esta [guía](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/
+). Un entorno virtual facilita el manejo de proyectos y evita problemas de compatibilidad entre dependencias.
+
+Comienza por crear un entorno virtual en el directorio de tu proyecto:
+
+```bash
+python -m venv .env
+```
+
+Activa el entorno virtual:
+
+```bash
+source .env/bin/activate
+```
+
+Ahora puedes instalar 🤗 Transformers con el siguiente comando:
+
+```bash
+pip install transformers
+```
+
+Solo para CPU, puedes instalar 🤗 Transformers y una biblioteca de deep learning con un comando de una sola línea.
+
+Por ejemplo, instala 🤗 Transformers y Pytorch:
+
+```bash
+pip install transformers[torch]
+```
+
+🤗 Transformers y TensorFlow 2.0:
+
+```bash
+pip install transformers[tf-cpu]
+```
+
+🤗 Transformers y Flax:
+
+```bash
+pip install transformers[flax]
+```
+
+Por último, revisa si 🤗 Transformers ha sido instalada exitosamente con el siguiente comando que descarga un modelo pre-entrenado:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('we love you'))"
+```
+Después imprime la etiqueta y el puntaje:
+
+```bash
+[{'label': 'POSITIVE', 'score': 0.9998704791069031}]
+```
+
+## Instalación desde la fuente
+
+Instala 🤗 Transformers desde la fuente con el siguiente comando:
+
+```bash
+pip install git+https://github.com/huggingface/transformers
+```
+
+El comando de arriba instala la versión `master` más actual en vez de la última versión estable. La versión `master` es útil para obtener los últimos avances de 🤗 Transformers. Por ejemplo, se puede dar el caso de que un error fue corregido después de la última versión estable pero aún no se ha liberado un nuevo lanzamiento. Sin embargo, existe la posibilidad de que la versión `master` no sea estable. El equipo trata de mantener la versión `master` operacional y la mayoría de los errores son resueltos en unas cuantas horas o un día. Si encuentras algún problema, por favor abre un [Issue](https://github.com/huggingface/transformers/issues) para que pueda ser corregido más rápido.
+
+Verifica si 🤗 Transformers está instalada apropiadamente con el siguiente comando:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('I love you'))"
+```
+
+## Instalación editable
+
+Necesitarás una instalación editable si deseas:
+* Usar la versión `master` del código fuente.
+* Contribuir a 🤗 Transformers y necesitas probar cambios en el código.
+
+Clona el repositorio e instala 🤗 Transformers con los siguientes comandos:
+
+```bash
+git clone https://github.com/huggingface/transformers.git
+cd transformers
+pip install -e .
+```
+
+Éstos comandos van a ligar el directorio desde donde clonamos el repositorio al path de las bibliotecas de Python. Python ahora buscará dentro de la carpeta que clonaste además de los paths normales de la biblioteca. Por ejemplo, si los paquetes de Python se encuentran instalados en `~/anaconda3/envs/main/lib/python3.7/site-packages/`, Python también buscará en el directorio desde donde clonamos el repositorio `~/transformers/`.
+
+
+
+Debes mantener el directorio `transformers` si deseas seguir usando la biblioteca.
+
+
+
+Puedes actualizar tu copia local a la última versión de 🤗 Transformers con el siguiente comando:
+
+```bash
+cd ~/transformers/
+git pull
+```
+
+El entorno de Python que creaste para la instalación de 🤗 Transformers encontrará la versión `master` en la siguiente ejecución.
+
+## Instalación con conda
+
+Puedes instalar 🤗 Transformers desde el canal de conda `conda-forge` con el siguiente comando:
+
+```bash
+conda install conda-forge::transformers
+```
+
+## Configuración de Caché
+
+Los modelos preentrenados se descargan y almacenan en caché localmente en: `~/.cache/huggingface/transformers/`. Este es el directorio predeterminado proporcionado por la variable de entorno de shell `TRANSFORMERS_CACHE`. En Windows, el directorio predeterminado es dado por `C:\Users\username\.cache\huggingface\transformers`. Puedes cambiar las variables de entorno de shell que se muestran a continuación, en orden de prioridad, para especificar un directorio de caché diferente:
+
+1. Variable de entorno del shell (por defecto): `TRANSFORMERS_CACHE`.
+2. Variable de entorno del shell:`HF_HOME` + `transformers/`.
+3. Variable de entorno del shell: `XDG_CACHE_HOME` + `/huggingface/transformers`.
+
+
+
+🤗 Transformers usará las variables de entorno de shell `PYTORCH_TRANSFORMERS_CACHE` o `PYTORCH_PRETRAINED_BERT_CACHE` si viene de una iteración anterior de la biblioteca y ha configurado esas variables de entorno, a menos que especifiques la variable de entorno de shell `TRANSFORMERS_CACHE`.
+
+
+
+
+## Modo Offline
+
+🤗 Transformers puede ejecutarse en un entorno con firewall o fuera de línea (offline) usando solo archivos locales. Configura la variable de entorno `HF_HUB_OFFLINE=1` para habilitar este comportamiento.
+
+
+
+Puedes añadir [🤗 Datasets](https://huggingface.co/docs/datasets/) al flujo de entrenamiento offline declarando la variable de entorno `HF_DATASETS_OFFLINE=1`.
+
+
+
+Por ejemplo, normalmente ejecutarías un programa en una red normal con firewall para instancias externas con el siguiente comando:
+
+```bash
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+Ejecuta este mismo programa en una instancia offline con el siguiente comando:
+
+```bash
+HF_DATASETS_OFFLINE=1 HF_HUB_OFFLINE=1 \
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+El script ahora debería ejecutarse sin bloquearse ni esperar a que se agote el tiempo de espera porque sabe que solo debe buscar archivos locales.
+
+### Obtener modelos y tokenizers para uso offline
+
+Otra opción para usar 🤗 Transformers offline es descargando previamente los archivos y después apuntar al path local donde se encuentren. Hay tres maneras de hacer esto:
+
+* Descarga un archivo mediante la interfaz de usuario del [Model Hub](https://huggingface.co/models) haciendo click en el ícono ↓.
+
+ 
+
+
+* Utiliza el flujo de [`PreTrainedModel.from_pretrained`] y [`PreTrainedModel.save_pretrained`]:
+ 1. Descarga previamente los archivos con [`PreTrainedModel.from_pretrained`]:
+
+ ```py
+ >>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("bigscience/T0_3B")
+ >>> model = AutoModelForSeq2SeqLM.from_pretrained("bigscience/T0_3B")
+ ```
+
+
+ 2. Guarda los archivos en un directorio específico con [`PreTrainedModel.save_pretrained`]:
+
+ ```py
+ >>> tokenizer.save_pretrained("./your/path/bigscience_t0")
+ >>> model.save_pretrained("./your/path/bigscience_t0")
+ ```
+
+ 3. Cuando te encuentres offline, recarga los archivos con [`PreTrainedModel.from_pretrained`] desde el directorio especificado:
+
+ ```py
+ >>> tokenizer = AutoTokenizer.from_pretrained("./your/path/bigscience_t0")
+ >>> model = AutoModel.from_pretrained("./your/path/bigscience_t0")
+ ```
+
+* Descarga de manera programática los archivos con la biblioteca [huggingface_hub](https://github.com/huggingface/huggingface_hub/tree/main/src/huggingface_hub):
+
+ 1. Instala la biblioteca [huggingface_hub](https://github.com/huggingface/huggingface_hub/tree/main/src/huggingface_hub) en tu entorno virtual:
+
+ ```bash
+ python -m pip install huggingface_hub
+ ```
+
+ 2. Utiliza la función [`hf_hub_download`](https://huggingface.co/docs/hub/adding-a-library#download-files-from-the-hub) para descargar un archivo a un path específico. Por ejemplo, el siguiente comando descarga el archivo `config.json` del modelo [T0](https://huggingface.co/bigscience/T0_3B) al path deseado:
+
+ ```py
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> hf_hub_download(repo_id="bigscience/T0_3B", filename="config.json", cache_dir="./your/path/bigscience_t0")
+ ```
+
+Una vez que el archivo se descargue y se almacene en caché localmente, especifica tu ruta local para cargarlo y usarlo:
+
+```py
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("./your/path/bigscience_t0/config.json")
+```
+
+
+
+Para más detalles sobre cómo descargar archivos almacenados en el Hub consulta la sección [How to download files from the Hub](https://huggingface.co/docs/hub/how-to-downstream).
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/model_memory_anatomy.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/model_memory_anatomy.md
new file mode 100644
index 0000000000000000000000000000000000000000..6a220da993dba39d98493c60f123830436fc332b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/model_memory_anatomy.md
@@ -0,0 +1,239 @@
+
+
+# Anatomía del entrenamiento de los modelos
+
+Para entender las técnicas de optimización del rendimiento que se pueden aplicar para mejorar la eficiencia en la velocidad del entrenamiento de los modelos y la utilización de la memoria, es útil familiarizarse con cómo se utiliza la GPU durante el entrenamiento y cómo varía la intensidad de cálculo según la operación realizada.
+
+Empecemos explorando un ejemplo enfocado en la utilización de la GPU y la ejecución del entrenamiento de un modelo. Para la demostración, necesitaremos instalar algunas bibliotecas:
+
+```bash
+pip install transformers datasets accelerate nvidia-ml-py3
+```
+
+La biblioteca `nvidia-ml-py3` nos permite monitorear la utilización de memoria de los modelos desde Python. Es posible que estés familiarizado con el comando `nvidia-smi` en la terminal, esta biblioteca nos permite acceder a la misma información en Python directamente.
+
+Luego, creamos algunos datos ficticios: IDs de tokens aleatorios entre 100 y 30000 y etiquetas binarias para un clasificador. En total, obtenemos 512 secuencias cada una con longitud 512 y las almacenamos en un [`~datasets.Dataset`] con formato PyTorch.
+
+
+```py
+>>> import numpy as np
+>>> from datasets import Dataset
+
+
+>>> seq_len, dataset_size = 512, 512
+>>> dummy_data = {
+... "input_ids": np.random.randint(100, 30000, (dataset_size, seq_len)),
+... "labels": np.random.randint(0, 1, (dataset_size)),
+... }
+>>> ds = Dataset.from_dict(dummy_data)
+>>> ds.set_format("pt")
+```
+
+Para imprimir estadísticas resumidas para la utilización de la GPU y la ejecución del entrenamiento con [`Trainer`](https://huggingface.co/docs/transformers/en/main_classes/trainer#transformers.Trainer), definimos dos funciones auxiliares:
+
+```py
+>>> from pynvml import *
+
+
+>>> def print_gpu_utilization():
+... nvmlInit()
+... handle = nvmlDeviceGetHandleByIndex(0)
+... info = nvmlDeviceGetMemoryInfo(handle)
+... print(f"GPU memory occupied: {info.used//1024**2} MB.")
+
+
+>>> def print_summary(result):
+... print(f"Time: {result.metrics['train_runtime']:.2f}")
+... print(f"Samples/second: {result.metrics['train_samples_per_second']:.2f}")
+... print_gpu_utilization()
+```
+
+Comencemos comprobando que la memoria GPU este libre:
+
+```py
+>>> print_gpu_utilization()
+GPU memory occupied: 0 MB.
+```
+
+Parece estar bien: la memoria de la GPU no está ocupada como esperaríamos antes de cargar cualquier modelo. Si no es el caso en tu máquina, asegúrate de detener todos los procesos que estén utilizando la memoria de la GPU. Sin embargo, no toda la memoria libre de la GPU puede ser utilizada por el usuario. Cuando se carga un modelo en la GPU, también se cargan los kernels, lo que puede ocupar 1-2GB de memoria. Para ver cuánta memoria será ocupada por defecto, cargemos un tensor diminuto en la GPU, lo que también desencadena la carga de los kernels.
+
+```py
+>>> import torch
+
+
+>>> torch.ones((1, 1)).to("cuda")
+>>> print_gpu_utilization()
+GPU memory occupied: 1343 MB.
+```
+
+Vemos que los kernels solos ocupan 1,3GB de memoria de la GPU. Ahora, veamos cuánto espacio ocupa el modelo.
+
+## Cargar el Modelo
+
+Primero, cargamos el modelo `google-bert/bert-large-uncased`. Los pesos del modelo son cargados directamente en la GPU para que podamos verificar cuánto espacio ocupan solo los pesos.
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-large-uncased").to("cuda")
+>>> print_gpu_utilization()
+GPU memory occupied: 2631 MB.
+```
+
+Podemos ver que los pesos del modelo solos ocupan 1,3 GB de memoria de la GPU. El número exacto depende de la GPU específica que estés utilizando. Ten en cuenta que en GPUs más modernas, un modelo puede ocupar más espacio ya que los pesos se cargan de manera optimizada lo cual acelera el uso del modelo. Ahora también podemos verificar rápidamente si obtenemos el mismo resultado que con la CLI de `nvidia-smi`:
+
+```bash
+nvidia-smi
+```
+
+```bash
+Tue Jan 11 08:58:05 2022
++-----------------------------------------------------------------------------+
+| NVIDIA-SMI 460.91.03 Driver Version: 460.91.03 CUDA Version: 11.2 |
+|-------------------------------+----------------------+----------------------+
+| GPU Name Persistence-M| Bus-Id Disp.A | Volatile Uncorr. ECC |
+| Fan Temp Perf Pwr:Usage/Cap| Memory-Usage | GPU-Util Compute M. |
+| | | MIG M. |
+|===============================+======================+======================|
+| 0 Tesla V100-SXM2... On | 00000000:00:04.0 Off | 0 |
+| N/A 37C P0 39W / 300W | 2631MiB / 16160MiB | 0% Default |
+| | | N/A |
++-------------------------------+----------------------+----------------------+
+
++-----------------------------------------------------------------------------+
+| Processes: |
+| GPU GI CI PID Type Process name GPU Memory |
+| ID ID Usage |
+|=============================================================================|
+| 0 N/A N/A 3721 C ...nvs/codeparrot/bin/python 2629MiB |
++-----------------------------------------------------------------------------+
+```
+
+Obtenemos el mismo número que antes y también puedes ver que estamos utilizando una GPU V100 con 16GB de memoria. Ahora podemos empezar a entrenar el modelo y ver cómo cambia el consumo de memoria de la GPU. Primero, configuramos algunos argumentos de entrenamiento estándar:
+
+```py
+default_args = {
+ "output_dir": "tmp",
+ "eval_strategy": "steps",
+ "num_train_epochs": 1,
+ "log_level": "error",
+ "report_to": "none",
+}
+```
+
+
+
+Si planeas ejecutar varias pruebas, reinicie el kernel de Python entre cada prueba para borrar correctamente la memoria.
+
+
+
+## Utilización de la memoria en el entrenamiento
+
+Vamos a utilizar el [`Trainer`](https://huggingface.co/docs/transformers/en/main_classes/trainer#transformers.Trainer) y entrenar el modelo sin utilizar ninguna técnica de optimización del rendimiento de la GPU y un tamaño de lote de 4:
+
+```py
+>>> from transformers import TrainingArguments, Trainer, logging
+
+>>> logging.set_verbosity_error()
+
+
+>>> training_args = TrainingArguments(per_device_train_batch_size=4, **default_args)
+>>> trainer = Trainer(model=model, args=training_args, train_dataset=ds)
+>>> result = trainer.train()
+>>> print_summary(result)
+```
+
+```
+Time: 57.82
+Samples/second: 8.86
+GPU memory occupied: 14949 MB.
+```
+
+Vemos que incluso un tamaño de lote relativamente pequeño casi llena toda la memoria de nuestra GPU. Sin embargo, un tamaño de lote más grande a menudo puede resultar en una convergencia del modelo más rápida o un mejor rendimiento final. Así que idealmente queremos ajustar el tamaño del lote a las necesidades del modelo y no a las limitaciones de la GPU. Lo interesante es que utilizamos mucha más memoria que el tamaño del modelo.
+Para entender un poco mejor por qué es el caso, echemos un vistazo a las operaciones y necesidades de memoria de un modelo.
+
+## Anatomía de las Operaciones del Modelo
+
+La arquitectura de los transformers incluye 3 grupos principales de operaciones agrupadas a continuación por intensidad de cálculo.
+
+1. **Contracciones de Tensores**
+
+ Las capas lineales y componentes de la Atención Multi-Head realizan **multiplicaciones matriciales por lotes**. Estas operaciones son la parte más intensiva en cálculo del entrenamiento de los transformers.
+
+2. **Normalizaciones Estadísticas**
+
+ Softmax y normalización de capas son menos intensivas en cálculo que las contracciones de tensores, e implican una o más **operaciones de reducción**, cuyo resultado se aplica luego mediante un mapa.
+
+3. **Operadores por Elemento**
+
+ Estos son los operadores restantes: **sesgos, dropout, activaciones y conexiones residuales**. Estas son las operaciones menos intensivas en cálculo.
+
+Este conocimiento puede ser útil al analizar cuellos de botella de rendimiento.
+
+Este resumen se deriva de [Data Movement Is All You Need: A Case Study on Optimizing Transformers 2020](https://arxiv.org/abs/2007.00072)
+
+
+## Anatomía de la Memoria del Modelo
+
+Hemos visto que al entrenar un modelo se utiliza mucha más memoria que solo poner el modelo en la GPU. Esto se debe a que hay muchos componentes durante el entrenamiento que utilizan memoria de la GPU. Los componentes en memoria de la GPU son los siguientes:
+
+1. pesos del modelo
+2. estados del optimizador
+3. gradientes
+4. activaciones hacia adelante guardadas para el cálculo del gradiente
+5. buffers temporales
+6. memoria específica de funcionalidad
+
+Un modelo típico entrenado en precisión mixta con AdamW requiere 18 bytes por parámetro del modelo más memoria de activación. Para la inferencia no hay estados del optimizador ni gradientes, por lo que podemos restarlos. Y así terminamos con 6 bytes por parámetro del modelo para la inferencia en precisión mixta, más la memoria de activación.
+
+Veámoslo a detalle:
+
+**Pesos del Modelo:**
+
+- 4 bytes por número de parámetros para entrenamiento en fp32
+- 6 bytes por número de parámetros para entrenamiento en precisión mixta (mantiene un modelo en fp32 y uno en fp16 en memoria)
+
+**Estados del Optimizador:**
+
+- 8 bytes por número de parámetros para un AdamW normal (mantiene 2 estados)
+- 2 bytes por número de parámetros para optimizadores de 8 bits como [bitsandbytes](https://github.com/TimDettmers/bitsandbytes)
+- 4 bytes por número de parámetros para optimizadores como SGD con momentum (mantiene solo 1 estado)
+
+**Gradientes**
+
+- 4 bytes por número de parámetros para entrenamiento en fp32 o precisión mixta (los gradientes siempre se mantienen en fp32)
+
+**Activaciones hacia Adelante**
+
+- El tamaño depende de muchos factores, los principales siendo la longitud de la secuencia, el tamaño oculto y el tamaño de lote.
+
+Hay entradas y salidas que se pasan y se devuelven por las funciones hacia adelante y hacia atrás, y las activaciones hacia adelante (*forward activations*) guardadas para el cálculo del gradiente.
+
+**Memoria Temporal**
+
+Además, hay todas clases de variables temporales que se liberan una vez que se completa el cálculo, pero en el momento podrían requerir memoria adicional y podrían provocar un error de memoria insuficiente. Por lo tanto, al codificar es crucial pensar estratégicamente sobre tales variables temporales y a veces liberarlas explícitamente tan pronto como ya no se necesitan.
+
+**Memoria Específica de Funcionalidad**
+
+Entonces, su software podría tener necesidades especiales de memoria. Por ejemplo, al generar texto mediante la búsqueda por haz, el software necesita mantener múltiples copias de las entradas y salidas.
+
+**Velocidad de Ejecución `forward` vs `backward`**
+
+Para convoluciones y capas lineales, hay 2x flops en la ejecución hacia atrás (`backward`) en comparación con la ejecución hacia adelante (`forward`), lo que generalmente se traduce en ~2x más lento (a veces más, porque los tamaños en la ejecución hacia atrás tienden a ser más complejos). Las activaciones suelen ser limitadas por ancho de banda, y es típico que una activación tenga que leer más datos en la ejecución hacia atrás que en la ejecución hacia adelante (por ejemplo, la activación hacia adelante lee una vez, escribe una vez, la activación hacia atrás lee dos veces, gradOutput y salida de la ejecución hacia adelante, y escribe una vez, gradInput).
+
+Como puedes ver, hay potencialmente unos pocos lugares donde podríamos ahorrar memoria de la GPU o acelerar operaciones. Ahora que entiendes qué afecta la utilización de la GPU y la velocidad de cálculo, consulta la página de documentación [Métodos y herramientas para entrenamiento eficiente en una sola GPU](https://huggingface.co/docs/transformers/perf_train_gpu_one) para aprender sobre técnicas de optimización del rendimiento.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/model_sharing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/model_sharing.md
new file mode 100644
index 0000000000000000000000000000000000000000..77ee523094f4527549b2e19627a0e46fe230ff1a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/model_sharing.md
@@ -0,0 +1,223 @@
+
+
+# Compartir un modelo
+
+Los últimos dos tutoriales mostraron cómo puedes realizar fine-tunning a un modelo con PyTorch, Keras y 🤗 Accelerate para configuraciones distribuidas. ¡El siguiente paso es compartir tu modelo con la comunidad! En Hugging Face creemos en compartir abiertamente a todos el conocimiento y los recursos para democratizar la inteligencia artificial. En este sentido, te animamos a considerar compartir tu modelo con la comunidad, de esta forma ayudas a otros ahorrando tiempo y recursos.
+
+En este tutorial aprenderás dos métodos para compartir un modelo trained o fine-tuned en el [Model Hub](https://huggingface.co/models):
+
+- Mediante Código, enviando (push) tus archivos al Hub.
+- Con la interfaz Web, con Drag-and-drop de tus archivos al Hub.
+
+VIDEO
+
+
+
+Para compartir un modelo con la comunidad necesitas una cuenta en [huggingface.co](https://huggingface.co/join). También puedes unirte a una organización existente o crear una nueva.
+
+
+
+## Características de los repositorios
+
+Cada repositorio en el Model Hub se comporta como cualquier otro repositorio en GitHub. Nuestros repositorios ofrecen versioning, commit history, y la habilidad para visualizar diferencias.
+
+El versioning desarrollado dentro del Model Hub es basado en git y [git-lfs](https://git-lfs.github.com/). En otras palabras, puedes tratar un modelo como un repositorio, brindando un mejor control de acceso y escalabilidad. Version control permite *revisions*, un método para apuntar a una versión específica de un modelo utilizando un commit hash, tag o branch.
+
+Como resultado, puedes cargar una versión específica del modelo con el parámetro `revision`:
+
+```py
+>>> model = AutoModel.from_pretrained(
+... "julien-c/EsperBERTo-small", revision="4c77982" # tag name, or branch name, or commit hash
+... )
+```
+
+Los archivos son editados fácilmente dentro de un repositorio. Incluso puedes observar el commit history y las diferencias:
+
+
+
+## Configuración inicial
+
+Antes de compartir un modelo al Hub necesitarás tus credenciales de Hugging Face. Si tienes acceso a una terminal ejecuta el siguiente comando en el entorno virtual donde 🤗 Transformers esté instalado. Esto guardará tu token de acceso dentro de tu carpeta cache de Hugging Face (~/.cache/ by default):
+
+```bash
+huggingface-cli login
+```
+
+Si usas un notebook como Jupyter o Colaboratory, asegúrate de tener instalada la biblioteca [`huggingface_hub`](https://huggingface.co/docs/hub/adding-a-library). Esta biblioteca te permitirá interactuar por código con el Hub.
+
+```bash
+pip install huggingface_hub
+```
+
+Luego usa `notebook_login` para iniciar sesión al Hub, y sigue el link [aquí](https://huggingface.co/settings/token) para generar un token con el que iniciaremos sesión:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Convertir un modelo para todos los Frameworks
+
+Para asegurarnos que tu modelo pueda ser usado por alguien que esté trabajando con un framework diferente, te recomendamos convertir y subir tu modelo con checkpoints de pytorch y tensorflow. Aunque los usuarios aún son capaces de cargar su modelo desde un framework diferente, si se omite este paso será más lento debido a que 🤗 Transformers necesitará convertir el checkpoint sobre-la-marcha.
+
+Convertir un checkpoint para otro framework es fácil. Asegúrate tener Pytorch y TensorFlow instalado (Véase [aquí](installation) para instrucciones de instalación), y luego encuentra el modelo específico para tu tarea en el otro Framework.
+
+Por ejemplo, supongamos que has entrenado DistilBert para clasificación de secuencias en PyTorch y quieres convertirlo a su equivalente en TensorFlow. Cargas el equivalente en TensorFlow de tu modelo para tu tarea y especificas `from_pt=True` así 🤗 Transformers convertirá el Pytorch checkpoint a un TensorFlow Checkpoint:
+
+```py
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_pt=True)
+```
+
+Luego guardas tu nuevo modelo TensorFlow con su nuevo checkpoint:
+
+```py
+>>> tf_model.save_pretrained("path/to/awesome-name-you-picked")
+```
+
+De manera similar, especificas `from_tf=True` para convertir un checkpoint de TensorFlow a Pytorch:
+
+```py
+>>> pt_model = DistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_tf=True)
+>>> pt_model.save_pretrained("path/to/awesome-name-you-picked")
+```
+
+Si algún modelo está disponible en Flax, también puedes convertir un checkpoint de Pytorch a Flax:
+
+```py
+>>> flax_model = FlaxDistilBertForSequenceClassification.from_pretrained(
+... "path/to/awesome-name-you-picked", from_pt=True
+... )
+```
+
+## Compartir un modelo con `Trainer`
+
+
+
+Echa un vistazo a la documentación de [`pipeline`] para obtener una lista completa de tareas admitidas.
+
+
+
+## Uso del pipeline
+
+Si bien cada tarea tiene un [`pipeline`] asociado, es más sencillo usar la abstracción general [`pipeline`] que contiene todos los pipelines de tareas específicas. El [`pipeline`] carga automáticamente un modelo predeterminado y un tokenizador con capacidad de inferencia para tu tarea. Veamos el ejemplo de usar un [`pipeline`] para reconocimiento automático del habla (ASR), o texto a voz.
+
+1. Comienza creando un [`pipeline`] y específica una tarea de inferencia:
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline(task="automatic-speech-recognition")
+```
+
+2. Pasa tu entrada a la [`pipeline`]. En el caso del reconocimiento del habla, esto es un archivo de entrada de audio:
+
+```py
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': 'I HAVE A DREAM BUT ONE DAY THIS NATION WILL RISE UP LIVE UP THE TRUE MEANING OF ITS TREES'}
+```
+
+¿No es el resultado que tenías en mente? Echa un vistazo a algunos de los [modelos de reconocimiento automático del habla más descargados](https://huggingface.co/models?pipeline_tag=automatic-speech-recognition&sort=trending)
+en el Hub para ver si puedes obtener una mejor transcripción.
+
+Intentemos con el modelo [Whisper large-v2](https://huggingface.co/openai/whisper-large) de OpenAI. Whisper se lanzó
+2 años después que Wav2Vec2, y se entrenó con cerca de 10 veces más datos. Como tal, supera a Wav2Vec2 en la mayoría de las pruebas
+downstream. También tiene el beneficio adicional de predecir puntuación y mayúsculas, ninguno de los cuales es posible con
+Wav2Vec2.
+
+Vamos a probarlo aquí para ver cómo se desempeña:
+
+```py
+>>> transcriber = pipeline(model="openai/whisper-large-v2")
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+¡Ahora este resultado parece más preciso! Para una comparación detallada de Wav2Vec2 vs Whisper, consulta el [Curso de Transformers de Audio](https://huggingface.co/learn/audio-course/chapter5/asr_models).
+Realmente te animamos a que eches un vistazo al Hub para modelos en diferentes idiomas, modelos especializados en tu campo, y más.
+Puedes comparar directamente los resultados de los modelos desde tu navegador en el Hub para ver si se adapta o
+maneja casos de borde mejor que otros.
+Y si no encuentras un modelo para tu caso de uso, siempre puedes empezar a [entrenar](training) el tuyo propio.
+
+Si tienes varias entradas, puedes pasar tu entrada como una lista:
+
+```py
+transcriber(
+ [
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac",
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/1.flac",
+ ]
+)
+```
+
+Los pipelines son ideales para la experimentación, ya que cambiar de un modelo a otro es trivial; sin embargo, hay algunas formas de optimizarlas para cargas de trabajo más grandes que la experimentación. Consulta las siguientes guías que profundizan en iterar sobre conjuntos de datos completos o utilizar pipelines en un servidor web:
+de la documentación:
+
+* [Uso de pipelines en un conjunto de datos](#uso-de-pipelines-en-un-conjunto-de-datos)
+* [Uso de pipelines para un servidor web](./pipeline_webserver)
+
+## Parámetros
+
+[`pipeline`] admite muchos parámetros; algunos son específicos de la tarea y algunos son generales para todas las pipelines. En general, puedes especificar parámetros en cualquier lugar que desees:
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", my_parameter=1)
+
+out = transcriber(...) # This will use `my_parameter=1`.
+out = transcriber(..., my_parameter=2) # This will override and use `my_parameter=2`.
+out = transcriber(...) # This will go back to using `my_parameter=1`.
+```
+
+Vamos a echar un vistazo a tres importantes:
+
+### Device
+
+Si usas `device=n`, el pipeline automáticamente coloca el modelo en el dispositivo especificado. Esto funcionará independientemente de si estás utilizando PyTorch o Tensorflow.
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", device=0)
+```
+
+Si el modelo es demasiado grande para una sola GPU y estás utilizando PyTorch, puedes establecer `device_map="auto"` para determinar automáticamente cómo cargar y almacenar los pesos del modelo. Utilizar el argumento `device_map` requiere el paquete 🤗 [Accelerate](https://huggingface.co/docs/accelerate):
+
+```bash
+pip install --upgrade accelerate
+```
+
+El siguiente código carga y almacena automáticamente los pesos del modelo en varios dispositivos:
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", device_map="auto")
+```
+
+Tenga en cuenta que si se pasa `device_map="auto"`, no es necesario agregar el argumento `device=device` al instanciar tu `pipeline`, ¡ya que podrías encontrar algún comportamiento inesperado!
+
+### Batch size
+
+Por defecto, los pipelines no realizarán inferencia por lotes por razones explicadas en detalle [aquí](https://huggingface.co/docs/transformers/main_classes/pipelines#pipeline-batching). La razón es que la agrupación en lotes no es necesariamente más rápida y, de hecho, puede ser bastante más lenta en algunos casos.
+
+Pero si funciona en tu caso de uso, puedes utilizar:
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", device=0, batch_size=2)
+audio_filenames = [f"https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/{i}.flac" for i in range(1, 5)]
+texts = transcriber(audio_filenames)
+```
+
+Esto ejecuta el pipeline en los 4 archivos de audio proporcionados, pero los pasará en lotes de a 2 al modelo (que está en una GPU, donde la agrupación en lotes es más probable que ayude) sin requerir ningún código adicional de tu parte. La salida siempre debería coincidir con lo que habrías recibido sin agrupación en lotes. Solo se pretende como una forma de ayudarte a obtener más velocidad de una pipeline.
+
+Los pipelines también pueden aliviar algunas de las complejidades de la agrupación en lotes porque, para algunos pipelines, un solo elemento (como un archivo de audio largo) necesita ser dividido en varias partes para ser procesado por un modelo. El pipeline realiza esta [*agrupación en lotes de fragmentos*](https://huggingface.co/docs/transformers/main_classes/pipelines#pipeline-chunk-batching) por ti.
+
+### Task specific parameters
+
+Todas las tareas proporcionan parámetros específicos de la tarea que permiten flexibilidad adicional y opciones para ayudarte a completar tu trabajo. Por ejemplo, el método [`transformers.AutomaticSpeechRecognitionPipeline.__call__`] tiene un parámetro `return_timestamps` que suena prometedor para subtítulos de videos:
+
+```py
+>>> transcriber = pipeline(model="openai/whisper-large-v2", return_timestamps=True)
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.', 'chunks': [{'timestamp': (0.0, 11.88), 'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its'}, {'timestamp': (11.88, 12.38), 'text': ' creed.'}]}
+```
+
+Como puedes ver, el modelo infirió el texto y también salió **cuándo** se pronunciaron las distintas oraciones.
+
+Hay muchos parámetros disponibles para cada tarea, así que echa un vistazo a la referencia de la API de cada tarea para ver qué puedes ajustar. Por ejemplo, el [`~transformers.AutomaticSpeechRecognitionPipeline`] tiene un parámetro `chunk_length_s` que es útil para trabajar con archivos de audio realmente largos (por ejemplo, subtítulos de películas completas o videos de una hora de duración) que un modelo típicamente no puede manejar solo:
+
+```python
+>>> transcriber = pipeline(model="openai/whisper-large-v2", chunk_length_s=30)
+>>> transcriber("https://huggingface.co/datasets/reach-vb/random-audios/resolve/main/ted_60.wav")
+{'text': " So in college, I was a government major, which means I had to write a lot of papers. Now, when a normal student writes a paper, they might spread the work out a little like this. So, you know. You get started maybe a little slowly, but you get enough done in the first week that with some heavier days later on, everything gets done and things stay civil. And I would want to do that like that. That would be the plan. I would have it all ready to go, but then actually the paper would come along, and then I would kind of do this. And that would happen every single paper. But then came my 90-page senior thesis, a paper you're supposed to spend a year on. I knew for a paper like that, my normal workflow was not an option, it was way too big a project. So I planned things out and I decided I kind of had to go something like this. This is how the year would go. So I'd start off light and I'd bump it up"}
+```
+
+¡Si no puedes encontrar un parámetro que te ayude, no dudes en [solicitarlo](https://github.com/huggingface/transformers/issues/new?assignees=&labels=feature&template=feature-request.yml)!
+
+## Uso de pipelines en un conjunto de datos
+
+Los pipeline también puede ejecutar inferencia en un conjunto de datos grande. La forma más fácil que recomendamos para hacer esto es utilizando un iterador:
+
+```py
+def data():
+ for i in range(1000):
+ yield f"My example {i}"
+
+
+pipe = pipeline(model="openai-community/gpt2", device=0)
+generated_characters = 0
+for out in pipe(data()):
+ generated_characters += len(out[0]["generated_text"])
+```
+
+El iterador `data()` produce cada resultado, y el pipeline automáticamente
+reconoce que la entrada es iterable y comenzará a buscar los datos mientras
+continúa procesándolos en la GPU (dicho proceso utiliza [DataLoader](https://pytorch.org/docs/stable/data.html#torch.utils.data.DataLoader)). Esto es importante porque no tienes que asignar memoria para todo el conjunto de datos y puedes alimentar la GPU lo más rápido posible.
+
+Dado que la agrupación en lotes podría acelerar las cosas, puede ser útil intentar ajustar el parámetro `batch_size` aquí.
+
+La forma más sencilla de iterar sobre un conjunto de datos es cargandolo desde 🤗 [Datasets](https://github.com/huggingface/datasets/):
+
+```py
+# KeyDataset is a util that will just output the item we're interested in.
+from transformers.pipelines.pt_utils import KeyDataset
+from datasets import load_dataset
+
+pipe = pipeline(model="hf-internal-testing/tiny-random-wav2vec2", device=0)
+dataset = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation[:10]")
+
+for out in pipe(KeyDataset(dataset, "audio")):
+ print(out)
+```
+
+## Uso de pipelines para un servidor web
+
+
+Crear un motor de inferencia es un tema complejo que merece su propia página.
+
+
+[Link](./pipeline_webserver)
+
+## Pipeline de visión
+
+Usar un [`pipeline`] para tareas de visión es prácticamente idéntico.
+
+Especifica tu tarea y pasa tu imagen al clasificador. La imagen puede ser un enlace, una ruta local o una imagen codificada en base64. Por ejemplo, ¿qué especie de gato se muestra a continuación?
+
+
+
+```py
+>>> from transformers import pipeline
+
+>>> vision_classifier = pipeline(model="google/vit-base-patch16-224")
+>>> preds = vision_classifier(
+... images="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4335, 'label': 'lynx, catamount'}, {'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}, {'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}, {'score': 0.0239, 'label': 'Egyptian cat'}, {'score': 0.0229, 'label': 'tiger cat'}]
+```
+
+## Pipeline de texto
+
+Usar un [`pipeline`] para tareas de PLN es prácticamente idéntico.
+
+```py
+>>> from transformers import pipeline
+
+>>> # This model is a `zero-shot-classification` model.
+>>> # It will classify text, except you are free to choose any label you might imagine
+>>> classifier = pipeline(model="facebook/bart-large-mnli")
+>>> classifier(
+... "I have a problem with my iphone that needs to be resolved asap!!",
+... candidate_labels=["urgent", "not urgent", "phone", "tablet", "computer"],
+... )
+{'sequence': 'I have a problem with my iphone that needs to be resolved asap!!', 'labels': ['urgent', 'phone', 'computer', 'not urgent', 'tablet'], 'scores': [0.504, 0.479, 0.013, 0.003, 0.002]}
+```
+
+## Pipeline multimodal
+
+[`pipeline`] admite más de una modalidad. Por ejemplo, una tarea de respuesta a preguntas visuales (VQA) combina texto e imagen. No dudes en usar cualquier enlace de imagen que desees y una pregunta que quieras hacer sobre la imagen. La imagen puede ser una URL o una ruta local a la imagen.
+
+Por ejemplo, si usas esta [imagen de factura](https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png):
+
+```py
+>>> from transformers import pipeline
+
+>>> vqa = pipeline(model="impira/layoutlm-document-qa")
+>>> output = vqa(
+... image="https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png",
+... question="What is the invoice number?",
+... )
+>>> output[0]["score"] = round(output[0]["score"], 3)
+>>> output
+[{'score': 0.425, 'answer': 'us-001', 'start': 16, 'end': 16}]
+```
+
+
+
+Para ejecutar el ejemplo anterior, debe tener instalado [`pytesseract`](https://pypi.org/project/pytesseract/) además de 🤗 Transformers:
+
+```bash
+sudo apt install -y tesseract-ocr
+pip install pytesseract
+```
+
+
+
+## Uso de `pipeline` en modelos grandes con 🤗 `accelerate`:
+
+¡Puedes ejecutar fácilmente `pipeline` en modelos grandes utilizando 🤗 `accelerate`! Primero asegúrate de haber instalado `accelerate` con `pip install accelerate`.
+
+¡Luego carga tu modelo utilizando `device_map="auto"`! Utilizaremos `facebook/opt-1.3b` para nuestro ejemplo.
+
+```py
+# pip install accelerate
+import torch
+from transformers import pipeline
+
+pipe = pipeline(model="facebook/opt-1.3b", torch_dtype=torch.bfloat16, device_map="auto")
+output = pipe("This is a cool example!", do_sample=True, top_p=0.95)
+```
+
+También puedes pasar modelos cargados de 8 bits sí instalas `bitsandbytes` y agregas el argumento `load_in_8bit=True`
+
+```py
+# pip install accelerate bitsandbytes
+import torch
+from transformers import pipeline
+
+pipe = pipeline(model="facebook/opt-1.3b", device_map="auto", model_kwargs={"load_in_8bit": True})
+output = pipe("This is a cool example!", do_sample=True, top_p=0.95)
+```
+
+Nota que puedes reemplazar el punto de control con cualquier modelo de Hugging Face que admita la carga de modelos grandes, como BLOOM.
+
+## Crear demos web desde pipelines con `gradio`
+
+Los pipelines están automáticamente soportadas en [Gradio](https://github.com/gradio-app/gradio/), una biblioteca que hace que crear aplicaciones de aprendizaje automático hermosas y fáciles de usar en la web sea un proceso sencillo. Primero, asegúrate de tener Gradio instalado:
+
+```
+pip install gradio
+```
+
+Luego, puedes crear una demo web alrededor de una pipeline de clasificación de imágenes (o cualquier otra pipeline) en una sola línea de código llamando a la función `Interface.from_pipeline` de Gradio para lanzar la pipeline. Esto crea una interfaz intuitiva *drag-and-drop* en tu navegador:
+
+```py
+from transformers import pipeline
+import gradio as gr
+
+pipe = pipeline("image-classification", model="google/vit-base-patch16-224")
+
+gr.Interface.from_pipeline(pipe).launch()
+```
+
+
+
+
+De forma predeterminada, la demo web se ejecuta en un servidor local. Si deseas compartirlo con otros, puedes generar un enlace público temporal estableciendo `share=True` en `launch()`. También puedes hospedar tu demo en [Hugging Face Spaces](https://huggingface.co/spaces) para un enlace permanente.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/pipeline_webserver.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/pipeline_webserver.md
new file mode 100644
index 0000000000000000000000000000000000000000..e268daabcbe881a617fad0cfd41c24d32bb78992
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/pipeline_webserver.md
@@ -0,0 +1,128 @@
+
+
+# Uso de un flujo de trabajo para un servidor web
+
+
+Crear un motor de inferencia es un tema complejo, y la "mejor" solución probablemente dependerá de tu caso de uso. ¿Estás en CPU o en GPU? ¿Quieres la latencia más baja, el rendimiento más alto, soporte para muchos modelos o simplemente optimizar altamente un modelo específico? Hay muchas formas de abordar este tema, así que lo que vamos a presentar es un buen valor predeterminado para comenzar, que no necesariamente será la solución más óptima para ti.
+
+
+
+Lo fundamental para entender es que podemos usar un iterador, tal como [en un conjunto de datos](pipeline_tutorial#uso-de-pipelines-en-un-conjunto-de-datos), ya que un servidor web es básicamente un sistema que espera solicitudes y las trata a medida que llegan.
+
+Por lo general, los servidores web están multiplexados (multihilo, asíncrono, etc.) para manejar varias solicitudes simultáneamente. Por otro lado, los flujos de trabajo (y principalmente los modelos subyacentes) no son realmente ideales para el paralelismo; consumen mucha RAM, por lo que es mejor darles todos los recursos disponibles cuando se están ejecutando o es un trabajo intensivo en cómputo.
+
+Vamos a resolver esto haciendo que el servidor web maneje la carga ligera de recibir y enviar solicitudes, y que un único hilo maneje el trabajo real. Este ejemplo va a utilizar `starlette`. El marco de trabajo no es realmente importante, pero es posible que debas ajustar o cambiar el código si estás utilizando otro para lograr el mismo efecto.
+
+Crear `server.py`:
+
+```py
+from starlette.applications import Starlette
+from starlette.responses import JSONResponse
+from starlette.routing import Route
+from transformers import pipeline
+import asyncio
+
+
+async def homepage(request):
+ payload = await request.body()
+ string = payload.decode("utf-8")
+ response_q = asyncio.Queue()
+ await request.app.model_queue.put((string, response_q))
+ output = await response_q.get()
+ return JSONResponse(output)
+
+
+async def server_loop(q):
+ pipe = pipeline(model="google-bert/bert-base-uncased")
+ while True:
+ (string, response_q) = await q.get()
+ out = pipe(string)
+ await response_q.put(out)
+
+
+app = Starlette(
+ routes=[
+ Route("/", homepage, methods=["POST"]),
+ ],
+)
+
+
+@app.on_event("startup")
+async def startup_event():
+ q = asyncio.Queue()
+ app.model_queue = q
+ asyncio.create_task(server_loop(q))
+```
+
+Ahora puedes empezar con:
+```bash
+uvicorn server:app
+```
+
+Y puedes consultarlo con:
+```bash
+curl -X POST -d "test [MASK]" http://localhost:8000/
+#[{"score":0.7742936015129089,"token":1012,"token_str":".","sequence":"test."},...]
+```
+
+¡Y listo, ahora tienes una buena idea de cómo crear un servidor web!
+
+Lo realmente importante es cargar el modelo solo **una vez**, de modo que no haya copias del modelo en el servidor web. De esta manera, no se utiliza RAM innecesariamente. Luego, el mecanismo de queuing (colas) te permite hacer cosas sofisticadas como acumular algunos elementos antes de inferir para usar el agrupamiento dinámico:
+
+
+
+El ejemplo de código a continuación está escrito intencionalmente como pseudocódigo para facilitar la lectura.
+¡No lo ejecutes sin verificar si tiene sentido para los recursos de tu sistema!
+
+
+
+```py
+(string, rq) = await q.get()
+strings = []
+queues = []
+while True:
+ try:
+ (string, rq) = await asyncio.wait_for(q.get(), timeout=0.001) # 1ms
+ except asyncio.exceptions.TimeoutError:
+ break
+ strings.append(string)
+ queues.append(rq)
+strings
+outs = pipe(strings, batch_size=len(strings))
+for rq, out in zip(queues, outs):
+ await rq.put(out)
+```
+
+Nuevamente, el código propuesto está optimizado para la legibilidad, no para ser el mejor código.
+En primer lugar, no hay límite de tamaño de lote, lo cual generalmente no es una buena idea. Luego, el tiempo de espera se restablece en cada obtención de la cola, lo que significa que podrías esperar mucho más de 1ms antes de ejecutar la inferencia (retrasando la primera solicitud en esa cantidad).
+
+Sería mejor tener un único plazo de 1ms.
+
+Esto siempre esperará 1ms incluso si la cola está vacía, lo que podría no ser lo mejor ya que probablemente quieras comenzar a hacer inferencias si no hay nada en la cola. Pero tal vez tenga sentido si el agrupamiento es realmente crucial para tu caso de uso. Nuevamente, no hay una solución única y mejor.
+
+
+## Algunas cosas que podrías considerar
+
+### Comprobación de errores
+
+Hay muchas cosas que pueden salir mal en producción: falta de memoria, falta de espacio, cargar el modelo podría fallar, la consulta podría ser incorrecta, la consulta podría ser correcta pero aún así fallar debido a una mala configuración del modelo, y así sucesivamente.
+
+Generalmente, es bueno que el servidor muestre los errores al usuario, por lo que agregar muchos bloques `try..except` para mostrar esos errores es una buena idea. Pero ten en cuenta que también puede ser un riesgo de seguridad revelar todos esos errores dependiendo de tu contexto de seguridad.
+
+### Interrupción de circuito
+
+Los servidores web suelen verse mejor cuando hacen interrupciones de circuitos. Significa que devuelven errores adecuados cuando están sobrecargados en lugar de simplemente esperar la consulta indefinidamente. Devolver un error 503 en lugar de esperar un tiempo muy largo o un error 504 después de mucho tiempo.
+
+Esto es relativamente fácil de implementar en el código propuesto ya que hay una sola cola. Mirar el tamaño de la cola es una forma básica de empezar a devolver errores antes de que tu servidor web falle bajo carga.
+
+### Bloqueo del hilo principal
+
+Actualmente, PyTorch no es consciente de la asincronía, y el cálculo bloqueará el hilo principal mientras se ejecuta. Esto significa que sería mejor si PyTorch se viera obligado a ejecutarse en su propio hilo/proceso. Esto no se hizo aquí porque el código es mucho más complejo (principalmente porque los hilos, la asincronía y las colas no se llevan bien juntos). Pero en última instancia, hace lo mismo.
+
+Esto sería importante si la inferencia de elementos individuales fuera larga (> 1s) porque en este caso, significa que cada consulta durante la inferencia tendría que esperar 1s antes de recibir incluso un error.
+
+### Procesamiento por lotes dinámico
+
+En general, el procesamiento por lotes no es necesariamente una mejora respecto a pasar 1 elemento a la vez (ver [procesamiento por lotes](https://huggingface.co/docs/transformers/main_classes/pipelines#pipeline-batching) para más información). Pero puede ser muy efectivo cuando se usa en el entorno correcto. En la API, no hay procesamiento por lotes dinámico por defecto (demasiada oportunidad para una desaceleración). Pero para la inferencia de BLOOM - que es un modelo muy grande - el procesamiento por lotes dinámico es **esencial** para proporcionar una experiencia decente para todos.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/pr_checks.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/pr_checks.md
new file mode 100644
index 0000000000000000000000000000000000000000..ba67e85306d3a9d9944f263ad79a70182b170d31
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/pr_checks.md
@@ -0,0 +1,132 @@
+
+
+# Verificaciones en un Pull Request
+
+Cuando abres un _pull request_ en 🤗 Transformers, se ejecutarán una serie de verificaciones para asegurarte de que el _patch_ que estás agregando no rompa nada existente. Estas verificaciones son de cuatro tipos:
+- pruebas regulares
+- creación de la documentación
+- estilo del código y documentación
+- consistencia del repositorio
+
+En este documento, intentaremos explicar cuáles son esas diferentes verificaciones y el motivo detrás de ellas, así como también cómo depurarlas localmente si una falla en tu PR.
+
+Recuerda que todas las verificaciones requieren que tengas una instalación de desarrollo:
+
+```bash
+pip install transformers[dev]
+```
+
+o una instalación editable:
+
+```bash
+pip install -e .[dev]
+```
+
+del repositorio de Transformers.
+
+## Pruebas
+
+Todos los procesos que comienzan con `ci/circleci: run_tests_` ejecutan partes del conjunto de pruebas de Transformers. Cada uno de esos procesos se enfoca en una parte de la biblioteca en un entorno determinado: por ejemplo, `ci/circleci: run_tests_pipelines_tf` ejecuta la prueba de _pipelines_ en un entorno donde solo está instalado TensorFlow.
+
+Ten en cuenta que para evitar ejecutar pruebas cuando no hay un cambio real en los módulos que estás probando, solo se ejecuta una parte del conjunto de pruebas: se ejecuta una tarea auxiliar para determinar las diferencias en la biblioteca antes y después del PR (lo que GitHub te muestra en la pestaña "Files changes") y selecciona las pruebas afectadas por esa diferencia. Este auxiliar se puede ejecutar localmente usando:
+
+```bash
+python utils/tests_fetcher.py
+```
+
+desde el directorio raiz del repositorio de Transformers. Se ejecutará lo siguiente:
+
+1. Verificación para cada archivo en el _diff_ si los cambios están en el código, solo en comentarios o _docstrings_. Solo los archivos con cambios reales de código se conservan.
+2. Creación de un mapa interno que proporciona para cada archivo del código fuente de la biblioteca todos los archivos a los que impacta recursivamente. Se dice que el módulo A impacta al módulo B si el módulo B importa el módulo A. Para el impacto recursivo, necesitamos una cadena de módulos que va del módulo A al módulo B en la que cada módulo importa el anterior.
+3. Aplicación de este mapa en los archivos recopilados en el paso 1, lo que nos da una lista de archivos modelo afectados por el PR.
+4. Asignación de cada uno de esos archivos a sus archivos de prueba correspondientes y para obtener una la lista de pruebas a ejecutar.
+
+Al ejecutar el _script_ localmente, debes obtener los resultados de los pasos 1, 3 y 4 impresos y así saber qué pruebas se ejecutarán. El _script_ también creará un archivo llamado `test_list.txt` que contiene la lista de pruebas para ejecutar, y puede ejecutarlas localmente con el siguiente comando:
+
+```bash
+python -m pytest -n 8 --dist=loadfile -rA -s $(cat test_list.txt)
+```
+
+En caso de que se te escape algo, el conjunto completo de pruebas también se ejecuta a diario.
+
+## Creación de la documentación
+
+El proceso `build_pr_documentation` compila y genera una vista previa de la documentación para asegurarse de que todo se vea bien una vez que se fusione tu PR. Un bot agregará un enlace para obtener una vista previa de la documentación en tu PR. Cualquier cambio que realices en el PR se actualiza automáticamente en la vista previa. Si la documentación no se genera, haz clic en **Detalles** junto al proceso fallido para ver dónde salió mal. A menudo, el error es tan simple como que falta un archivo en `toctree`.
+
+Si estás interesado en compilar u obtener una vista previa de la documentación localmente, echa un vistazo al [`README.md`](https://github.com/huggingface/transformers/tree/main/docs) en la carpeta `docs`.
+
+## Estilo de código y documentación.
+
+El formato de código se aplica a todos los archivos fuente, los ejemplos y las pruebas utilizando `black` e `ruff`. También tenemos una herramienta personalizada que se ocupa del formato de los _docstrings_ y archivos `rst` (`utils/style_doc.py`), así como del orden de las importaciones _lazy_ realizadas en los archivos `__init__.py` de Transformers (`utils /custom_init_isort.py`). Todo esto se puede probar ejecutando
+
+```bash
+make style
+```
+
+CI verifica que se hayan aplicado dentro de la verificación `ci/circleci: check_code_quality`. También se ejecuta `ruff`, que hará una verificación básica a tu código y te hará saber si encuentra una variable no definida, o una que no se usa. Para ejecutar esa verificación localmente, usa
+
+```bash
+make quality
+```
+
+Esto puede llevar mucho tiempo, así que para ejecutar lo mismo solo en los archivos que modificaste en la rama actual, ejecuta
+
+```bash
+make fixup
+```
+
+Este último comando también ejecutará todas las verificaciones adicionales para la consistencia del repositorio. Echemos un vistazo a estas pruebas.
+
+## Consistencia del repositorio
+
+Esta verificación reagrupa todas las pruebas para asegurarse de que tu PR deja el repositorio en buen estado, y se realiza mediante `ci/circleci: check_repository_consistency`. Puedes ejecutar localmente esta verificación ejecutando lo siguiente:
+
+```bash
+make repo-consistency
+```
+
+Esta instrucción verifica que:
+
+- Todos los objetos agregados al _init_ están documentados (realizados por `utils/check_repo.py`)
+- Todos los archivos `__init__.py` tienen el mismo contenido en sus dos secciones (realizado por `utils/check_inits.py`)
+- Todo el código identificado como una copia de otro módulo es consistente con el original (realizado por `utils/check_copies.py`)
+- Todas las clases de configuración tienen al menos _checkpoint_ válido mencionado en sus _docstrings_ (realizado por `utils/check_config_docstrings.py`)
+- Las traducciones de los README y el índice del documento tienen la misma lista de modelos que el README principal (realizado por `utils/check_copies.py`)
+- Las tablas generadas automaticamente en la documentación están actualizadas (realizadas por `utils/check_table.py`)
+- La biblioteca tiene todos los objetos disponibles incluso si no están instaladas todas las dependencias opcionales (realizadas por `utils/check_dummies.py`)
+
+Si esta verificación falla, los primeros dos elementos requieren una reparación manual, los últimos cuatro pueden repararse automáticamente ejecutando el comando
+
+```bash
+make fix-copies
+```
+
+Las verificaciones adicionales se refieren a los PRs que agregan nuevos modelos, principalmente que:
+
+- Todos los modelos agregados están en un Auto-mapping (realizado por `utils/check_repo.py`)
+
+- Todos los modelos se verifican correctamente (realizados por `utils/check_repo.py`)
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/preprocessing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/preprocessing.md
new file mode 100644
index 0000000000000000000000000000000000000000..8486d6a0687abc296559a099884df6d6ae48cae2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/preprocessing.md
@@ -0,0 +1,560 @@
+
+
+# Preprocesamiento
+
+[[open-in-colab]]
+
+Antes de que puedas utilizar los datos en un modelo, debes procesarlos en un formato aceptable para el modelo. Un modelo no entiende el texto en bruto, las imágenes o el audio. Estas entradas necesitan ser convertidas en números y ensambladas en tensores. En este tutorial, podrás:
+
+* Preprocesar los datos textuales con un tokenizador.
+* Preprocesar datos de imagen o audio con un extractor de características.
+* Preprocesar datos para una tarea multimodal con un procesador.
+
+## NLP
+
+
+
+Si tienes previsto utilizar un modelo pre-entrenado, es importante que utilices el tokenizador pre-entrenado asociado. Esto te asegura que el texto se divide de la misma manera que el corpus de pre-entrenamiento y utiliza el mismo índice de tokens correspondiente (usualmente referido como el *vocab*) durante el pre-entrenamiento.
+
+
+
+Comienza rápidamente cargando un tokenizador pre-entrenado con la clase [`AutoTokenizer`]. Esto descarga el *vocab* utilizado cuando un modelo es pre-entrenado.
+
+### Tokenizar
+
+Carga un tokenizador pre-entrenado con [`AutoTokenizer.from_pretrained`]:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
+```
+
+A continuación, pasa tu frase al tokenizador:
+
+```py
+>>> encoded_input = tokenizer("Do not meddle in the affairs of wizards, for they are subtle and quick to anger.")
+>>> print(encoded_input)
+{'input_ids': [101, 2079, 2025, 19960, 10362, 1999, 1996, 3821, 1997, 16657, 1010, 2005, 2027, 2024, 11259, 1998, 4248, 2000, 4963, 1012, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+El tokenizador devuelve un diccionario con tres ítems importantes:
+
+* [input_ids](glossary#input-ids) son los índices correspondientes a cada token de la frase.
+* [attention_mask](glossary#attention-mask) indica si un token debe ser atendido o no.
+* [token_type_ids](glossary#token-type-ids) identifica a qué secuencia pertenece un token cuando hay más de una secuencia.
+
+Tu puedes decodificar el `input_ids` para devolver la entrada original:
+
+```py
+>>> tokenizer.decode(encoded_input["input_ids"])
+'[CLS] Do not meddle in the affairs of wizards, for they are subtle and quick to anger. [SEP]'
+```
+
+Como puedes ver, el tokenizador ha añadido dos tokens especiales - `CLS` y `SEP` (clasificador y separador) - a la frase. No todos los modelos necesitan
+tokens especiales, pero si lo llegas a necesitar, el tokenizador los añadirá automáticamente.
+
+Si hay varias frases que quieres preprocesar, pasa las frases como una lista al tokenizador:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_inputs = tokenizer(batch_sentences)
+>>> print(encoded_inputs)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1]]}
+```
+
+### Pad
+
+Esto nos lleva a un tema importante. Cuando se procesa un batch de frases, no siempre tienen la misma longitud. Esto es un problema porque los tensores que se introducen en el modelo deben tener una forma uniforme. El pad es una estrategia para asegurar que los tensores sean rectangulares añadiendo un "padding token" especial a las oraciones con menos tokens.
+
+Establece el parámetro `padding` en `True` aplicando el pad a las secuencias más cortas del batch para que coincidan con la secuencia más larga:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True)
+>>> print(encoded_input)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
+```
+
+Observa que el tokenizador ha aplicado el pad a la primera y la tercera frase con un "0" porque son más cortas.
+
+### Truncamiento
+
+En el otro extremo del espectro, a veces una secuencia puede ser demasiado larga para un modelo. En este caso, tendrás que truncar la secuencia a una longitud más corta.
+
+Establece el parámetro `truncation` a `True` para truncar una secuencia a la longitud máxima aceptada por el modelo:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True)
+>>> print(encoded_input)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
+```
+
+### Construye tensores
+
+Finalmente, si quieres que el tokenizador devuelva los tensores reales que se introducen en el modelo.
+
+Establece el parámetro `return_tensors` como `pt` para PyTorch, o `tf` para TensorFlow:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch, padding=True, truncation=True, return_tensors="pt")
+>>> print(encoded_input)
+{'input_ids': tensor([[ 101, 153, 7719, 21490, 1122, 1114, 9582, 1623, 102],
+ [ 101, 5226, 1122, 9649, 1199, 2610, 1236, 102, 0]]),
+ 'token_type_ids': tensor([[0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0]]),
+ 'attention_mask': tensor([[1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 1, 0]])}
+===PT-TF-SPLIT===
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch, padding=True, truncation=True, return_tensors="tf")
+>>> print(encoded_input)
+{'input_ids': ,
+ 'token_type_ids': ,
+ 'attention_mask': }
+```
+
+## Audio
+
+Las entradas de audio se preprocesan de forma diferente a las entradas textuales, pero el objetivo final es el mismo: crear secuencias numéricas que el modelo pueda entender. Un [extractor de características](main_classes/feature_extractor) (o feature extractor en inglés) está diseñado para extraer características de datos provenientes de imágenes o audio sin procesar y convertirlos en tensores. Antes de empezar, instala 🤗 Datasets para cargar un dataset de audio para experimentar:
+
+```bash
+pip install datasets
+```
+
+Carga la tarea de detección de palabras clave del benchmark [SUPERB](https://huggingface.co/datasets/superb) (consulta el [tutorial 🤗 Dataset](https://huggingface.co/docs/datasets/load_hub) para que obtengas más detalles sobre cómo cargar un dataset):
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("superb", "ks")
+```
+
+Accede al primer elemento de la columna `audio` para echar un vistazo a la entrada. Al llamar a la columna `audio` se cargará y volverá a muestrear automáticamente el archivo de audio:
+
+```py
+>>> dataset["train"][0]["audio"]
+{'array': array([ 0. , 0. , 0. , ..., -0.00592041,
+ -0.00405884, -0.00253296], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/05734a36d88019a09725c20cc024e1c4e7982e37d7d55c0c1ca1742ea1cdd47f/_background_noise_/doing_the_dishes.wav',
+ 'sampling_rate': 16000}
+```
+
+Esto devuelve tres elementos:
+
+* `array` es la señal de voz cargada - y potencialmente remuestreada - como un array 1D.
+* `path` apunta a la ubicación del archivo de audio.
+* `sampling_rate` se refiere a cuántos puntos de datos de la señal de voz se miden por segundo.
+
+### Resample
+
+Para este tutorial, se utilizará el modelo [Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base). Como puedes ver en la model card, el modelo Wav2Vec2 está pre-entrenado en audio de voz muestreado a 16kHz. Es importante que la tasa de muestreo de tus datos de audio coincida con la tasa de muestreo del dataset utilizado para pre-entrenar el modelo. Si la tasa de muestreo de tus datos no es la misma, deberás volver a muestrear tus datos de audio.
+
+Por ejemplo, carga el dataset [LJ Speech](https://huggingface.co/datasets/lj_speech) que tiene una tasa de muestreo de 22050kHz. Para utilizar el modelo Wav2Vec2 con este dataset, reduce la tasa de muestreo a 16kHz:
+
+```py
+>>> lj_speech = load_dataset("lj_speech", split="train")
+>>> lj_speech[0]["audio"]
+{'array': array([-7.3242188e-04, -7.6293945e-04, -6.4086914e-04, ...,
+ 7.3242188e-04, 2.1362305e-04, 6.1035156e-05], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/917ece08c95cf0c4115e45294e3cd0dee724a1165b7fc11798369308a465bd26/LJSpeech-1.1/wavs/LJ001-0001.wav',
+ 'sampling_rate': 22050}
+```
+
+1. Usa el método 🤗 Datasets' [`cast_column`](https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.cast_column) para reducir la tasa de muestreo a 16kHz:
+
+```py
+>>> lj_speech = lj_speech.cast_column("audio", Audio(sampling_rate=16_000))
+```
+
+2. Carga el archivo de audio:
+
+```py
+>>> lj_speech[0]["audio"]
+{'array': array([-0.00064146, -0.00074657, -0.00068768, ..., 0.00068341,
+ 0.00014045, 0. ], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/917ece08c95cf0c4115e45294e3cd0dee724a1165b7fc11798369308a465bd26/LJSpeech-1.1/wavs/LJ001-0001.wav',
+ 'sampling_rate': 16000}
+```
+
+Como puedes ver, el `sampling_rate` se ha reducido a 16kHz. Ahora que sabes cómo funciona el resampling, volvamos a nuestro ejemplo anterior con el dataset SUPERB.
+
+### Extractor de características
+
+El siguiente paso es cargar un extractor de características para normalizar y aplicar el pad a la entrada. Cuando se aplica padding a los datos textuales, se añade un "0" para las secuencias más cortas. La misma idea se aplica a los datos de audio y el extractor de características de audio añadirá un "0" - interpretado como silencio - al "array".
+
+Carga el extractor de características con [`AutoFeatureExtractor.from_pretrained`]:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base")
+```
+
+Pasa el `array` de audio al extractor de características. También te recomendamos añadir el argumento `sampling_rate` en el extractor de características para poder depurar mejor los errores silenciosos que puedan producirse.
+
+```py
+>>> audio_input = [dataset["train"][0]["audio"]["array"]]
+>>> feature_extractor(audio_input, sampling_rate=16000)
+{'input_values': [array([ 0.00045439, 0.00045439, 0.00045439, ..., -0.1578519 , -0.10807519, -0.06727459], dtype=float32)]}
+```
+
+### Pad y truncamiento
+
+Al igual que el tokenizador, puedes aplicar padding o truncamiento para manejar secuencias variables en un batch. Fíjate en la longitud de la secuencia de estas dos muestras de audio:
+
+```py
+>>> dataset["train"][0]["audio"]["array"].shape
+(1522930,)
+
+>>> dataset["train"][1]["audio"]["array"].shape
+(988891,)
+```
+
+Como puedes ver, el `sampling_rate` se ha reducido a 16kHz.
+
+```py
+>>> def preprocess_function(examples):
+... audio_arrays = [x["array"] for x in examples["audio"]]
+... inputs = feature_extractor(
+... audio_arrays,
+... sampling_rate=16000,
+... padding=True,
+... max_length=1000000,
+... truncation=True,
+... )
+... return inputs
+```
+
+Aplica la función a los primeros ejemplos del dataset:
+
+```py
+>>> processed_dataset = preprocess_function(dataset["train"][:5])
+```
+
+Ahora echa un vistazo a las longitudes de las muestras procesadas:
+
+```py
+>>> processed_dataset["input_values"][0].shape
+(1000000,)
+
+>>> processed_dataset["input_values"][1].shape
+(1000000,)
+```
+
+Las longitudes de las dos primeras muestras coinciden ahora con la longitud máxima especificada.
+
+## Visión
+
+También se utiliza un extractor de características para procesar imágenes para tareas de visión por computadora. Una vez más, el objetivo es convertir la imagen en bruto en un batch de tensores como entrada.
+
+Vamos a cargar el dataset [food101](https://huggingface.co/datasets/food101) para este tutorial. Usa el parámetro 🤗 Datasets `split` para cargar solo una pequeña muestra de la división de entrenamiento ya que el dataset es bastante grande:
+
+```py
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("food101", split="train[:100]")
+```
+
+A continuación, observa la imagen con la función 🤗 Datasets [`Image`](https://huggingface.co/docs/datasets/package_reference/main_classes?highlight=image#datasets.Image):
+
+```py
+>>> dataset[0]["image"]
+```
+
+
+
+### Extractor de características
+
+Carga el extractor de características con [`AutoFeatureExtractor.from_pretrained`]:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("google/vit-base-patch16-224")
+```
+
+### Aumento de Datos
+
+Para las tareas de visión por computadora es común añadir algún tipo de aumento de datos (o data augmentation) a las imágenes como parte del preprocesamiento. Puedes añadir el método de aumento de datos con cualquier librería que quieras, pero en este tutorial utilizarás el módulo [`transforms`](https://pytorch.org/vision/stable/transforms.html) de torchvision.
+
+1. Normaliza la imagen y utiliza [`Compose`](https://pytorch.org/vision/master/generated/torchvision.transforms.Compose.html) para encadenar algunas transformaciones - [`RandomResizedCrop`](https://pytorch.org/vision/main/generated/torchvision.transforms.RandomResizedCrop.html) y [`ColorJitter`](https://pytorch.org/vision/main/generated/torchvision.transforms.ColorJitter.html) - juntas:
+
+```py
+>>> from torchvision.transforms import Compose, Normalize, RandomResizedCrop, ColorJitter, ToTensor
+
+>>> normalize = Normalize(mean=feature_extractor.image_mean, std=feature_extractor.image_std)
+>>> _transforms = Compose(
+... [RandomResizedCrop(feature_extractor.size), ColorJitter(brightness=0.5, hue=0.5), ToTensor(), normalize]
+... )
+```
+
+2. El modelo acepta [`pixel_values`](model_doc/visionencoderdecoder#transformers.VisionEncoderDecoderModel.forward.pixel_values) como entrada. Este valor es generado por el extractor de características. Crea una función que genere `pixel_values` a partir de las transformaciones:
+
+```py
+>>> def transforms(examples):
+... examples["pixel_values"] = [_transforms(image.convert("RGB")) for image in examples["image"]]
+... return examples
+```
+
+3. A continuación, utiliza 🤗 Datasets [`set_transform`](https://huggingface.co/docs/datasets/process#format-transform) para aplicar las transformaciones sobre la marcha:
+
+```py
+>>> dataset.set_transform(transforms)
+```
+
+4. Ahora, cuando accedes a la imagen, observarás que el extractor de características ha añadido a la entrada del modelo `pixel_values`:
+
+```py
+>>> dataset[0]["image"]
+{'image': ,
+ 'label': 6,
+ 'pixel_values': tensor([[[ 0.0353, 0.0745, 0.1216, ..., -0.9922, -0.9922, -0.9922],
+ [-0.0196, 0.0667, 0.1294, ..., -0.9765, -0.9843, -0.9922],
+ [ 0.0196, 0.0824, 0.1137, ..., -0.9765, -0.9686, -0.8667],
+ ...,
+ [ 0.0275, 0.0745, 0.0510, ..., -0.1137, -0.1216, -0.0824],
+ [ 0.0667, 0.0824, 0.0667, ..., -0.0588, -0.0745, -0.0980],
+ [ 0.0353, 0.0353, 0.0431, ..., -0.0039, -0.0039, -0.0588]],
+
+ [[ 0.2078, 0.2471, 0.2863, ..., -0.9451, -0.9373, -0.9451],
+ [ 0.1608, 0.2471, 0.3098, ..., -0.9373, -0.9451, -0.9373],
+ [ 0.2078, 0.2706, 0.3020, ..., -0.9608, -0.9373, -0.8275],
+ ...,
+ [-0.0353, 0.0118, -0.0039, ..., -0.2392, -0.2471, -0.2078],
+ [ 0.0196, 0.0353, 0.0196, ..., -0.1843, -0.2000, -0.2235],
+ [-0.0118, -0.0039, -0.0039, ..., -0.0980, -0.0980, -0.1529]],
+
+ [[ 0.3961, 0.4431, 0.4980, ..., -0.9216, -0.9137, -0.9216],
+ [ 0.3569, 0.4510, 0.5216, ..., -0.9059, -0.9137, -0.9137],
+ [ 0.4118, 0.4745, 0.5216, ..., -0.9137, -0.8902, -0.7804],
+ ...,
+ [-0.2314, -0.1922, -0.2078, ..., -0.4196, -0.4275, -0.3882],
+ [-0.1843, -0.1686, -0.2000, ..., -0.3647, -0.3804, -0.4039],
+ [-0.1922, -0.1922, -0.1922, ..., -0.2941, -0.2863, -0.3412]]])}
+```
+
+Este es el aspecto de la imagen después de preprocesarla. Como era de esperar por las transformaciones aplicadas, la imagen ha sido recortada aleatoriamente y sus propiedades de color son diferentes.
+
+```py
+>>> import numpy as np
+>>> import matplotlib.pyplot as plt
+
+>>> img = dataset[0]["pixel_values"]
+>>> plt.imshow(img.permute(1, 2, 0))
+```
+
+
+
+## Multimodal
+
+Para las tareas multimodales utilizarás una combinación de todo lo que has aprendido hasta ahora y aplicarás tus habilidades a una tarea de reconocimiento automático de voz (ASR). Esto significa que necesitarás un:
+
+* Extractor de características para preprocesar los datos de audio.
+* Un tokenizador para procesar el texto.
+
+Volvamos al dataset [LJ Speech](https://huggingface.co/datasets/lj_speech):
+
+```py
+>>> from datasets import load_dataset
+
+>>> lj_speech = load_dataset("lj_speech", split="train")
+```
+
+Suponiendo que te interesan principalmente las columnas `audio` y `texto`, elimina las demás columnas:
+
+```py
+>>> lj_speech = lj_speech.map(remove_columns=["file", "id", "normalized_text"])
+```
+
+Ahora echa un vistazo a las columnas `audio` y `texto`:
+
+```py
+>>> lj_speech[0]["audio"]
+{'array': array([-7.3242188e-04, -7.6293945e-04, -6.4086914e-04, ...,
+ 7.3242188e-04, 2.1362305e-04, 6.1035156e-05], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/917ece08c95cf0c4115e45294e3cd0dee724a1165b7fc11798369308a465bd26/LJSpeech-1.1/wavs/LJ001-0001.wav',
+ 'sampling_rate': 22050}
+
+>>> lj_speech[0]["text"]
+'Printing, in the only sense with which we are at present concerned, differs from most if not from all the arts and crafts represented in the Exhibition'
+```
+
+Recuerda la sección anterior sobre el procesamiento de datos de audio, siempre debes [volver a muestrear](preprocessing#audio) la tasa de muestreo de tus datos de audio para que coincida con la tasa de muestreo del dataset utilizado para preentrenar un modelo:
+
+```py
+>>> lj_speech = lj_speech.cast_column("audio", Audio(sampling_rate=16_000))
+```
+
+### Processor
+
+Un processor combina un extractor de características y un tokenizador. Cargue un procesador con [`AutoProcessor.from_pretrained`]:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base-960h")
+```
+
+1. Crea una función para procesar los datos de audio en `input_values`, y tokeniza el texto en `labels`. Estas son las entradas del modelo:
+
+```py
+>>> def prepare_dataset(example):
+... audio = example["audio"]
+
+... example.update(processor(audio=audio["array"], text=example["text"], sampling_rate=16000))
+
+... return example
+```
+
+2. Aplica la función `prepare_dataset` a una muestra:
+
+```py
+>>> prepare_dataset(lj_speech[0])
+```
+
+Observa que el método processor ha añadido `input_values` y `labels`. La tasa de muestreo también se ha reducido correctamente a 16kHz.
+
+Genial, ahora deberías ser capaz de preprocesar datos para cualquier modalidad e incluso combinar diferentes modalidades. En el siguiente tutorial, aprenderás aplicar fine tuning a un modelo en tus datos recién preprocesados.
+
+## Todo lo que siempre quisiste saber sobre el padding y el truncamiento
+
+Hemos visto los comandos que funcionarán para la mayoría de los casos (hacer pad a tu batch teniendo en cuenta la longitud de la frase máxima y
+truncar a la longitud máxima que el modelo puede aceptar). Sin embargo, la API admite más estrategias si las necesitas. Los
+tres argumentos que necesitas conocer para ello son `padding`, `truncation` y `max_length`.
+
+- `padding` controla el aplicarme padding al texto. Puede ser un booleano o una cadena que debe ser:
+
+ - `True` o `'longest'` para aplicar el pad hasta la secuencia más larga del batch (no apliques el padding si sólo le proporcionas
+ una sola secuencia).
+ - `'max_length'` para aplicar el pad hasta la longitud especificada por el argumento `max_length` o la longitud máxima aceptada
+ por el modelo si no le proporcionas `longitud_máxima` (`longitud_máxima=None`). Si sólo le proporcionas una única secuencia
+ se le aplicará el padding.
+ `False` o `'do_not_pad'` para no aplicar pad a las secuencias. Como hemos visto antes, este es el comportamiento por
+ defecto.
+
+- `truncation` controla el truncamiento. Puede ser un booleano o una string que debe ser:
+
+ - `True` o `'longest_first'` truncan hasta la longitud máxima especificada por el argumento `max_length` o
+ la longitud máxima aceptada por el modelo si no le proporcionas `max_length` (`max_length=None`). Esto
+ truncará token por token, eliminando un token de la secuencia más larga del par hasta alcanzar la longitud
+ adecuada.
+ - `'only_second'` trunca hasta la longitud máxima especificada por el argumento `max_length` o la
+ longitud máxima aceptada por el modelo si no le proporcionas `max_length` (`max_length=None`). Esto sólo truncará
+ la segunda frase de un par si le proporcionas un par de secuencias (o un batch de pares de secuencias).
+ - `'only_first'` trunca hasta la longitud máxima especificada por el argumento `max_length` o la longitud máxima
+ aceptada por el modelo si no se proporciona `max_length` (`max_length=None`). Esto sólo truncará
+ la primera frase de un par si se proporciona un par de secuencias (o un lote de pares de secuencias).
+ - `False` o `'do_not_truncate'` para no truncar las secuencias. Como hemos visto antes, este es el comportamiento
+ por defecto.
+
+- `max_length` para controlar la longitud del padding/truncamiento. Puede ser un número entero o `None`, en cuyo caso
+será por defecto la longitud máxima que el modelo puede aceptar. Si el modelo no tiene una longitud máxima de entrada específica, el
+padding/truncamiento a `longitud_máxima` se desactiva.
+
+A continuación te mostramos en una tabla que resume la forma recomendada de configurar el padding y el truncamiento. Si utilizas un par de secuencias de entrada en
+algunos de los siguientes ejemplos, puedes sustituir `truncation=True` por una `STRATEGY` seleccionada en
+`['only_first', 'only_second', 'longest_first']`, es decir, `truncation='only_second'` o `truncation= 'longest_first'` para controlar cómo se truncan ambas secuencias del par como se ha detallado anteriormente.
+
+| Truncation | Padding | Instrucciones |
+|--------------------------------------|-----------------------------------|---------------------------------------------------------------------------------------------|
+| no truncation | no padding | `tokenizer(batch_sentences)` |
+| | padding secuencia max del batch | `tokenizer(batch_sentences, padding=True)` or |
+| | | `tokenizer(batch_sentences, padding='longest')` |
+| | padding long max de input model | `tokenizer(batch_sentences, padding='max_length')` |
+| | padding a una long especifica | `tokenizer(batch_sentences, padding='max_length', max_length=42)` |
+| truncation long max del input model | no padding | `tokenizer(batch_sentences, truncation=True)` or |
+| | | `tokenizer(batch_sentences, truncation=STRATEGY)` |
+| | padding secuencia max del batch | `tokenizer(batch_sentences, padding=True, truncation=True)` or |
+| | | `tokenizer(batch_sentences, padding=True, truncation=STRATEGY)` |
+| | padding long max de input model | `tokenizer(batch_sentences, padding='max_length', truncation=True)` or |
+| | | `tokenizer(batch_sentences, padding='max_length', truncation=STRATEGY)` |
+| | padding a una long especifica | Not possible |
+| truncation a una long especifica | no padding | `tokenizer(batch_sentences, truncation=True, max_length=42)` or |
+| | | `tokenizer(batch_sentences, truncation=STRATEGY, max_length=42)` |
+| | padding secuencia max del batch | `tokenizer(batch_sentences, padding=True, truncation=True, max_length=42)` or |
+| | | `tokenizer(batch_sentences, padding=True, truncation=STRATEGY, max_length=42)` |
+| | padding long max de input model | Not possible |
+| | padding a una long especifica | `tokenizer(batch_sentences, padding='max_length', truncation=True, max_length=42)` or |
+| | | `tokenizer(batch_sentences, padding='max_length', truncation=STRATEGY, max_length=42)` |
+
+
+
+
+
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/quicktour.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/quicktour.md
new file mode 100644
index 0000000000000000000000000000000000000000..c4babab09f023df427320dbd9c6ce26ff0eb24da
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/quicktour.md
@@ -0,0 +1,401 @@
+
+
+# Tour rápido
+
+[[open-in-colab]]
+
+¡Entra en marcha con los 🤗 Transformers! Comienza usando [`pipeline`] para una inferencia veloz, carga un modelo preentrenado y un tokenizador con una [AutoClass](./model_doc/auto) para resolver tu tarea de texto, visión o audio.
+
+
+
+Todos los ejemplos de código presentados en la documentación tienen un botón arriba a la derecha para elegir si quieres ocultar o mostrar el código en Pytorch o TensorFlow.
+Si no fuese así, se espera que el código funcione para ambos backends sin ningún cambio.
+
+
+
+## Pipeline
+
+[`pipeline`] es la forma más fácil de usar un modelo preentrenado para una tarea dada.
+
+
+
+Para más detalles acerca del [`pipeline`] y tareas asociadas, consulta la documentación [aquí](./main_classes/pipelines).
+
+
+
+### Uso del Pipeline
+
+En el siguiente ejemplo, usarás el [`pipeline`] para análisis de sentimiento.
+
+Instala las siguientes dependencias si aún no lo has hecho:
+
+
+
+
+```bash
+pip install torch
+```
+
+
+
+```bash
+pip install tensorflow
+```
+
+
+
+Importa [`pipeline`] y especifica la tarea que deseas completar:
+
+```py
+>>> from transformers import pipeline
+
+>>> clasificador = pipeline("sentiment-analysis", model="pysentimiento/robertuito-sentiment-analysis")
+```
+
+El pipeline descarga y almacena en caché el [modelo preentrenado](https://huggingface.co/pysentimiento/robertuito-sentiment-analysis) y tokeniza para análisis de sentimiento. Si no hubieramos elegido un modelo el pipeline habría elegido uno por defecto. Ahora puedes usar `clasificador` en tu texto objetivo:
+
+```py
+>>> clasificador("Estamos muy felices de mostrarte la biblioteca de 🤗 Transformers.")
+[{'label': 'POS', 'score': 0.9320}]
+```
+
+Para más de un enunciado, entrega una lista al [`pipeline`] que devolverá una lista de diccionarios:
+
+El [`pipeline`] también puede iterar sobre un dataset entero. Comienza instalando la biblioteca [🤗 Datasets](https://huggingface.co/docs/datasets/):
+
+```bash
+pip install datasets
+```
+
+Crea un [`pipeline`] con la tarea que deseas resolver y el modelo que quieres usar. Coloca el parámetro `device` a `0` para poner los tensores en un dispositivo CUDA:
+
+```py
+>>> import torch
+>>> from transformers import pipeline
+
+>>> reconocedor_de_voz = pipeline(
+... "automatic-speech-recognition", model="jonatasgrosman/wav2vec2-large-xlsr-53-spanish", device=0
+... )
+```
+
+A continuación, carga el dataset (ve 🤗 Datasets [Quick Start](https://huggingface.co/docs/datasets/quickstart.html) para más detalles) sobre el que quisieras iterar. Por ejemplo, vamos a cargar el dataset [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14):
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="es-ES", split="train") # doctest: +IGNORE_RESULT
+```
+
+Debemos asegurarnos de que la frecuencia de muestreo del conjunto de datos coincide con la frecuencia de muestreo con la que se entrenó `jonatasgrosman/wav2vec2-large-xlsr-53-spanish`.
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=reconocedor_de_voz.feature_extractor.sampling_rate))
+```
+
+Los archivos de audio se cargan y remuestrean automáticamente cuando llamamos a la columna `"audio"`.
+Extraigamos las matrices de onda cruda (raw waveform, en inglés) de las primeras 4 muestras y pasémosla como una lista al pipeline:
+
+```py
+>>> resultado = reconocedor_de_voz(dataset[:4]["audio"])
+>>> print([d["text"] for d in resultado])
+['ahora buenas eh a ver tengo un problema con vuestra aplicación resulta que que quiero hacer una transferencia bancaria a una cuenta conocida pero me da error la aplicación a ver que a ver que puede ser', 'la aplicación no cargue saldo de mi nueva cuenta', 'hola tengo un problema con la aplicación no carga y y tampoco veo que carga el saldo de mi cuenta nueva dice que la aplicación está siendo reparada y ahora no puedo acceder a mi cuenta no necesito inmediatamente', 'hora buena la aplicación no se carga la vida no carga el saldo de mi cuenta nueva dice que la villadenta siendo reparada y oro no puedo hacer a mi cuenta']
+```
+
+Para un dataset más grande, donde los inputs son de mayor tamaño (como en habla/audio o visión), querrás pasar un generador en lugar de una lista que carga todos los inputs en memoria. Ve la [documentación del pipeline](./main_classes/pipelines) para más información.
+
+### Usa otro modelo y otro tokenizador en el pipeline
+
+El [`pipeline`] puede acomodarse a cualquier modelo del [Model Hub](https://huggingface.co/models) haciendo más fácil adaptar el [`pipeline`] para otros casos de uso. Por ejemplo, si quisieras un modelo capaz de manejar texto en francés, usa los tags en el Model Hub para filtrar entre los modelos apropiados. El resultado mejor filtrado devuelve un [modelo BERT](https://huggingface.co/nlptown/bert-base-multilingual-uncased-sentiment) multilingual fine-tuned para el análisis de sentimiento. Genial, ¡vamos a usar este modelo!
+
+```py
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+```
+
+
+
+Usa [`AutoModelForSequenceClassification`] y ['AutoTokenizer'] para cargar un modelo preentrenado y un tokenizador asociado (más en un `AutoClass` debajo):
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+
+Usa [`TFAutoModelForSequenceClassification`] y ['AutoTokenizer'] para cargar un modelo preentrenado y un tokenizador asociado (más en un `TFAutoClass` debajo):
+
+```py
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+
+Después puedes especificar el modelo y el tokenizador en el [`pipeline`], y aplicar el `classifier` en tu texto objetivo:
+
+```py
+>>> classifier = pipeline("sentiment-analysis", model=model, tokenizer=tokenizer)
+>>> classifier("Nous sommes très heureux de vous présenter la bibliothèque 🤗 Transformers.")
+[{'label': '5 stars', 'score': 0.7273}]
+```
+
+Si no pudieras encontrar el modelo para tu caso respectivo de uso necesitarás ajustar un modelo preentrenado a tus datos. Mira nuestro [tutorial de fine-tuning](./training) para aprender cómo. Finalmente, después de que has ajustado tu modelo preentrenado, ¡por favor considera compartirlo (ve el tutorial [aquí](./model_sharing)) con la comunidad en el Model Hub para democratizar el NLP! 🤗
+
+## AutoClass
+
+
+
+
+```py
+>>> pt_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="pt",
+... )
+```
+
+
+
+```py
+>>> tf_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="tf",
+... )
+```
+
+
+
+Lee el tutorial de [preprocessing](./preprocessing) para más detalles acerca de la tokenización.
+
+### AutoModel
+
+
+
+🤗 Transformers provee una forma simple y unificada de cargar tus instancias preentrenadas. Esto significa que puedes cargar un [`AutoModel`] como cargarías un [`AutoTokenizer`]. La única diferencia es seleccionar el [`AutoModel`] correcto para la tarea. Ya que estás clasificando texto, o secuencias, carga [`AutoModelForSequenceClassification`]:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+Ve el [task summary](./task_summary) para revisar qué clase del [`AutoModel`] deberías usar para cada tarea.
+
+
+
+Ahora puedes pasar tu lote (batch) preprocesado de inputs directamente al modelo. Solo tienes que desempacar el diccionario añadiendo `**`:
+
+```py
+>>> pt_outputs = pt_model(**pt_batch)
+```
+
+El modelo producirá las activaciones finales en el atributo `logits`. Aplica la función softmax a `logits` para obtener las probabilidades:
+
+```py
+>>> from torch import nn
+
+>>> pt_predictions = nn.functional.softmax(pt_outputs.logits, dim=-1)
+>>> print(pt_predictions)
+tensor([[0.0021, 0.0018, 0.0115, 0.2121, 0.7725],
+ [0.2084, 0.1826, 0.1969, 0.1755, 0.2365]], grad_fn=)
+```
+
+
+🤗 Transformers provee una forma simple y unificada de cargar tus instancias preentrenadas. Esto significa que puedes cargar un [`TFAutoModel`] como cargarías un [`AutoTokenizer`]. La única diferencia es seleccionar el [`TFAutoModel`] correcto para la tarea. Ya que estás clasificando texto, o secuencias, carga [`TFAutoModelForSequenceClassification`]:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+ Ve el [task summary](./task_summary) para revisar qué clase del [`AutoModel`]
+ deberías usar para cada tarea.
+
+
+Ahora puedes pasar tu lote preprocesado de inputs directamente al modelo pasando las llaves del diccionario directamente a los tensores:
+
+```py
+>>> tf_outputs = tf_model(tf_batch)
+```
+
+El modelo producirá las activaciones finales en el atributo `logits`. Aplica la función softmax a `logits` para obtener las probabilidades:
+
+```py
+>>> import tensorflow as tf
+
+>>> tf_predictions = tf.nn.softmax(tf_outputs.logits, axis=-1)
+>>> print(tf.math.round(tf_predictions * 10**4) / 10**4)
+tf.Tensor(
+[[0.0021 0.0018 0.0116 0.2121 0.7725]
+ [0.2084 0.1826 0.1969 0.1755 0.2365]], shape=(2, 5), dtype=float32)
+```
+
+
+
+
+
+Todos los modelos de 🤗 Transformers (PyTorch o TensorFlow) producirán los tensores *antes* de la función de activación
+final (como softmax) porque la función de activación final es comúnmente fusionada con la pérdida.
+
+
+
+Los modelos son [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) o [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) estándares así que podrás usarlos en tu training loop usual. Sin embargo, para facilitar las cosas, 🤗 Transformers provee una clase [`Trainer`] para PyTorch que añade funcionalidades para entrenamiento distribuido, precición mixta, y más. Para TensorFlow, puedes usar el método `fit` desde [Keras](https://keras.io/). Consulta el [tutorial de entrenamiento](./training) para más detalles.
+
+
+
+Los outputs del modelo de 🤗 Transformers son dataclasses especiales por lo que sus atributos pueden ser completados en un IDE.
+Los outputs del modelo también se comportan como tuplas o diccionarios (e.g., puedes indexar con un entero, un slice o una cadena) en cuyo caso los atributos que son `None` son ignorados.
+
+
+
+### Guarda un modelo
+
+
+
+Una vez que se haya hecho fine-tuning a tu modelo puedes guardarlo con tu tokenizador usando [`PreTrainedModel.save_pretrained`]:
+
+```py
+>>> pt_save_directory = "./pt_save_pretrained"
+>>> tokenizer.save_pretrained(pt_save_directory) # doctest: +IGNORE_RESULT
+>>> pt_model.save_pretrained(pt_save_directory)
+```
+
+Cuando quieras usar el modelo otra vez cárgalo con [`PreTrainedModel.from_pretrained`]:
+
+```py
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("./pt_save_pretrained")
+```
+
+
+
+
+Una vez que se haya hecho fine-tuning a tu modelo puedes guardarlo con tu tokenizador usando [`TFPreTrainedModel.save_pretrained`]:
+
+```py
+>>> tf_save_directory = "./tf_save_pretrained"
+>>> tokenizer.save_pretrained(tf_save_directory) # doctest: +IGNORE_RESULT
+>>> tf_model.save_pretrained(tf_save_directory)
+```
+
+Cuando quieras usar el modelo otra vez cárgalo con [`TFPreTrainedModel.from_pretrained`]:
+
+```py
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("./tf_save_pretrained")
+```
+
+
+
+Una característica particularmente interesante de 🤗 Transformers es la habilidad de guardar el modelo y cargarlo como un modelo de PyTorch o TensorFlow. El parámetro `from_pt` o `from_tf` puede convertir el modelo de un framework al otro:
+
+
+
+
+```py
+>>> from transformers import AutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(pt_save_directory)
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(pt_save_directory, from_pt=True)
+```
+
+
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(tf_save_directory)
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(tf_save_directory, from_tf=True)
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/run_scripts.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/run_scripts.md
new file mode 100644
index 0000000000000000000000000000000000000000..d9a2b142a8ab6c9c2c9b287e479015afbd4eb279
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/run_scripts.md
@@ -0,0 +1,351 @@
+
+
+# Entrenamiento con scripts
+
+Junto con los [notebooks](./notebooks) de 🤗 Transformers, también hay scripts con ejemplos que muestran cómo entrenar un modelo para una tarea en [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch), [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow), o [JAX/Flax](https://github.com/huggingface/transformers/tree/main/examples/flax).
+
+También encontrarás scripts que hemos usado en nuestros [proyectos de investigación](https://github.com/huggingface/transformers/tree/main/examples/research_projects) y [ejemplos pasados](https://github.com/huggingface/transformers/tree/main/examples/legacy) que en su mayoría son aportados por la comunidad. Estos scripts no se mantienen activamente y requieren una versión específica de 🤗 Transformers que probablemente sea incompatible con la última versión de la biblioteca.
+
+No se espera que los scripts de ejemplo funcionen de inmediato en todos los problemas, y es posible que debas adaptar el script al problema que estás tratando de resolver. Para ayudarte con esto, la mayoría de los scripts exponen completamente cómo se preprocesan los datos, lo que te permite editarlos según sea necesario para tu caso de uso.
+
+Para cualquier característica que te gustaría implementar en un script de ejemplo, por favor discútelo en el [foro](https://discuss.huggingface.co/) o con un [issue](https://github.com/huggingface/transformers/issues) antes de enviar un Pull Request. Si bien agradecemos las correcciones de errores, es poco probable que fusionemos un Pull Request que agregue más funcionalidad a costa de la legibilidad.
+
+Esta guía te mostrará cómo ejecutar un ejemplo de un script de entrenamiento para resumir texto en [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization) y [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/summarization). Se espera que todos los ejemplos funcionen con ambos frameworks a menos que se especifique lo contrario.
+
+## Configuración
+
+Para ejecutar con éxito la última versión de los scripts de ejemplo debes **instalar 🤗 Transformers desde su fuente** en un nuevo entorno virtual:
+
+```bash
+git clone https://github.com/huggingface/transformers
+cd transformers
+pip install .
+```
+
+Para versiones anteriores de los scripts de ejemplo, haz clic en alguno de los siguientes links:
+
+
+ Ejemplos de versiones anteriores de 🤗 Transformers
+
+
+
+Luego cambia tu clon actual de 🤗 Transformers a una versión específica, por ejemplo v3.5.1:
+
+```bash
+git checkout tags/v3.5.1
+```
+
+Una vez que hayas configurado la versión correcta de la biblioteca, ve a la carpeta de ejemplo de tu elección e instala los requisitos específicos del ejemplo:
+
+```bash
+pip install -r requirements.txt
+```
+
+## Ejecutar un script
+
+
+
+El script de ejemplo descarga y preprocesa un conjunto de datos de la biblioteca 🤗 [Datasets](https://huggingface.co/docs/datasets/). Luego, el script ajusta un conjunto de datos con [Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) en una arquitectura que soporta la tarea de resumen. El siguiente ejemplo muestra cómo ajustar un [T5-small](https://huggingface.co/google-t5/t5-small) en el conjunto de datos [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail). El modelo T5 requiere un argumento adicional `source_prefix` debido a cómo fue entrenado. Este aviso le permite a T5 saber que se trata de una tarea de resumir.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+El script de ejemplo descarga y preprocesa un conjunto de datos de la biblioteca 🤗 [Datasets](https://huggingface.co/docs/datasets/). Luego, el script ajusta un conjunto de datos utilizando Keras en una arquitectura que soporta la tarea de resumir. El siguiente ejemplo muestra cómo ajustar un [T5-small](https://huggingface.co/google-t5/t5-small) en el conjunto de datos [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail). El modelo T5 requiere un argumento adicional `source_prefix` debido a cómo fue entrenado. Este aviso le permite a T5 saber que se trata de una tarea de resumir.
+
+```bash
+python examples/tensorflow/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## Entrenamiento distribuido y de precisión mixta
+
+[Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) admite un entrenamiento distribuido y de precisión mixta, lo que significa que también puedes usarlo en un script. Para habilitar ambas características:
+
+- Agrega el argumento `fp16` para habilitar la precisión mixta.
+- Establece la cantidad de GPU que se usará con el argumento `nproc_per_node`.
+
+```bash
+torchrun \
+ --nproc_per_node 8 pytorch/summarization/run_summarization.py \
+ --fp16 \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+Los scripts de TensorFlow utilizan [`MirroredStrategy`](https://www.tensorflow.org/guide/distributed_training#mirroredstrategy) para el entrenamiento distribuido, y no es necesario agregar argumentos adicionales al script de entrenamiento. El script de TensorFlow utilizará múltiples GPUs de forma predeterminada si están disponibles.
+
+## Ejecutar un script en una TPU
+
+
+
+Las Unidades de Procesamiento de Tensor (TPUs) están diseñadas específicamente para acelerar el rendimiento. PyTorch admite TPU con el compilador de aprendizaje profundo [XLA](https://www.tensorflow.org/xla) (consulta [aquí](https://github.com/pytorch/xla/blob/master/README.md) para obtener más detalles). Para usar una TPU, inicia el script `xla_spawn.py` y usa el argumento `num_cores` para establecer la cantidad de núcleos de TPU que deseas usar.
+
+```bash
+python xla_spawn.py --num_cores 8 \
+ summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+Las Unidades de Procesamiento de Tensor (TPUs) están diseñadas específicamente para acelerar el rendimiento. TensorFlow utiliza [`TPUStrategy`](https://www.tensorflow.org/guide/distributed_training#tpustrategy) para entrenar en TPUs. Para usar una TPU, pasa el nombre del recurso de la TPU al argumento `tpu`
+
+```bash
+python run_summarization.py \
+ --tpu name_of_tpu_resource \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## Ejecutar un script con 🤗 Accelerate
+
+🤗 [Accelerate](https://huggingface.co/docs/accelerate) es una biblioteca exclusiva de PyTorch que ofrece un método unificado para entrenar un modelo en varios tipos de configuraciones (solo CPU, GPU múltiples, TPU) mientras mantiene una visibilidad completa en el ciclo de entrenamiento de PyTorch. Asegúrate de tener 🤗 Accelerate instalado si aún no lo tienes:
+
+> Nota: Como Accelerate se está desarrollando rápidamente, debes instalar la versión git de Accelerate para ejecutar los scripts
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+En lugar del script `run_summarization.py`, debes usar el script `run_summarization_no_trainer.py`. Los scripts compatibles con 🤗 Accelerate tendrán un archivo `task_no_trainer.py` en la carpeta. Comienza ejecutando el siguiente comando para crear y guardar un archivo de configuración:
+
+```bash
+accelerate config
+```
+
+Prueba tu configuración para asegurarte que está configurada correctamente:
+
+```bash
+accelerate test
+```
+
+Todo listo para iniciar el entrenamiento:
+
+```bash
+accelerate launch run_summarization_no_trainer.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir ~/tmp/tst-summarization
+```
+
+## Usar un conjunto de datos personalizado
+
+El script de la tarea resumir admite conjuntos de datos personalizados siempre que sean un archivo CSV o JSON Line. Cuando uses tu propio conjunto de datos, necesitas especificar varios argumentos adicionales:
+
+- `train_file` y `validation_file` especifican la ruta a tus archivos de entrenamiento y validación.
+- `text_column` es el texto de entrada para resumir.
+- `summary_column` es el texto de destino para la salida.
+
+Un script para resumir que utiliza un conjunto de datos personalizado se vera así:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --train_file path_to_csv_or_jsonlines_file \
+ --validation_file path_to_csv_or_jsonlines_file \
+ --text_column text_column_name \
+ --summary_column summary_column_name \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --overwrite_output_dir \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --predict_with_generate
+```
+
+## Prueba un script
+
+A veces, es una buena idea ejecutar tu secuencia de comandos en una cantidad menor de ejemplos para asegurarte de que todo funciona como se espera antes de comprometerte con un conjunto de datos completo, lo que puede demorar horas en completarse. Utiliza los siguientes argumentos para truncar el conjunto de datos a un número máximo de muestras:
+
+- `max_train_samples`
+- `max_eval_samples`
+- `max_predict_samples`
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --max_train_samples 50 \
+ --max_eval_samples 50 \
+ --max_predict_samples 50 \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+No todos los scripts de ejemplo admiten el argumento `max_predict_samples`. Puede que desconozcas si la secuencia de comandos admite este argumento, agrega `-h` para verificar:
+
+```bash
+examples/pytorch/summarization/run_summarization.py -h
+```
+
+## Reanudar el entrenamiento desde el punto de control
+
+Otra opción útil para habilitar es reanudar el entrenamiento desde un punto de control anterior. Esto asegurará que puedas continuar donde lo dejaste sin comenzar de nuevo si tu entrenamiento se interrumpe. Hay dos métodos para reanudar el entrenamiento desde un punto de control.
+
+El primer método utiliza el argumento `output_dir previous_output_dir` para reanudar el entrenamiento desde el último punto de control almacenado en `output_dir`. En este caso, debes eliminar `overwrite_output_dir`:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --output_dir previous_output_dir \
+ --predict_with_generate
+```
+
+El segundo método utiliza el argumento `resume_from_checkpoint path_to_specific_checkpoint` para reanudar el entrenamiento desde una carpeta de punto de control específica.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --resume_from_checkpoint path_to_specific_checkpoint \
+ --predict_with_generate
+```
+
+## Comparte tu modelo
+
+Todos los scripts pueden cargar tu modelo final en el [Model Hub](https://huggingface.co/models). Asegúrate de haber iniciado sesión en Hugging Face antes de comenzar:
+
+```bash
+huggingface-cli login
+```
+
+Luego agrega el argumento `push_to_hub` al script. Este argumento creará un repositorio con tu nombre de usuario Hugging Face y el nombre de la carpeta especificado en `output_dir`.
+
+Para darle a tu repositorio un nombre específico, usa el argumento `push_to_hub_model_id` para añadirlo. El repositorio se incluirá automáticamente en tu namespace.
+
+El siguiente ejemplo muestra cómo cargar un modelo con un nombre de repositorio específico:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --push_to_hub \
+ --push_to_hub_model_id finetuned-t5-cnn_dailymail \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/sagemaker.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/sagemaker.md
new file mode 100644
index 0000000000000000000000000000000000000000..9bc5b74108419865a04b64388bbf49d6d5878aab
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/sagemaker.md
@@ -0,0 +1,28 @@
+
+
+# Ejecutar el entrenamiento en Amazon SageMaker
+
+La documentación ha sido trasladada a [hf.co/docs/sagemaker](https://huggingface.co/docs/sagemaker). Esta página será eliminada en `transformers` 5.0.
+
+### Tabla de contenido
+
+- [Entrenar modelos de Hugging Face en Amazon SageMaker con SageMaker Python SDK](https://huggingface.co/docs/sagemaker/train)
+- [Desplegar modelos de Hugging Face en Amazon SageMaker con SageMaker Python SDK](https://huggingface.co/docs/sagemaker/inference)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/serialization.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/serialization.md
new file mode 100644
index 0000000000000000000000000000000000000000..3ad7d08985305327301b9d385d20949de5260962
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/serialization.md
@@ -0,0 +1,674 @@
+
+
+# Exportar modelos 🤗 Transformers
+
+Si necesitas implementar modelos 🤗 Transformers en entornos de producción, te
+recomendamos exportarlos a un formato serializado que se pueda cargar y ejecutar
+en tiempos de ejecución y hardware especializados. En esta guía, te mostraremos cómo
+exportar modelos 🤗 Transformers en dos formatos ampliamente utilizados: ONNX y TorchScript.
+
+Una vez exportado, un modelo puede optimizarse para la inferencia a través de técnicas
+como la cuantización y _pruning_. Si estás interesado en optimizar tus modelos para
+que funcionen con la máxima eficiencia, consulta la
+[biblioteca de 🤗 Optimum](https://github.com/huggingface/optimum).
+
+## ONNX
+
+El proyecto [ONNX (Open Neural Network eXchange)](http://onnx.ai) es un
+estándar abierto que define un conjunto común de operadores y un formato
+de archivo común para representar modelos de aprendizaje profundo en una
+amplia variedad de _frameworks_, incluidos PyTorch y TensorFlow. Cuando un modelo
+se exporta al formato ONNX, estos operadores se usan para construir un
+grafo computacional (a menudo llamado _representación intermedia_) que
+representa el flujo de datos a través de la red neuronal.
+
+Al exponer un grafo con operadores y tipos de datos estandarizados, ONNX facilita
+el cambio entre frameworks. Por ejemplo, un modelo entrenado en PyTorch se puede
+exportar a formato ONNX y luego importar en TensorFlow (y viceversa).
+
+🤗 Transformers proporciona un paquete llamado `transformers.onnx`, el cual permite convertir
+los checkpoints de un modelo en un grafo ONNX aprovechando los objetos de configuración.
+Estos objetos de configuración están hechos a la medida de diferentes arquitecturas de modelos
+y están diseñados para ser fácilmente extensibles a otras arquitecturas.
+
+Las configuraciones a la medida incluyen las siguientes arquitecturas:
+
+
+
+- ALBERT
+- BART
+- BEiT
+- BERT
+- BigBird
+- BigBird-Pegasus
+- Blenderbot
+- BlenderbotSmall
+- BLOOM
+- CamemBERT
+- CLIP
+- CodeGen
+- ConvBERT
+- ConvNeXT
+- ConvNeXTV2
+- Data2VecText
+- Data2VecVision
+- DeBERTa
+- DeBERTa-v2
+- DeiT
+- DETR
+- DistilBERT
+- ELECTRA
+- FlauBERT
+- GPT Neo
+- GPT-J
+- I-BERT
+- LayoutLM
+- LayoutLMv3
+- LeViT
+- LongT5
+- M2M100
+- Marian
+- mBART
+- MobileBERT
+- MobileViT
+- MT5
+- OpenAI GPT-2
+- Perceiver
+- PLBart
+- ResNet
+- RoBERTa
+- RoFormer
+- SqueezeBERT
+- T5
+- ViT
+- XLM
+- XLM-RoBERTa
+- XLM-RoBERTa-XL
+- YOLOS
+
+En las próximas dos secciones, te mostraremos cómo:
+
+* Exportar un modelo compatible utilizando el paquete `transformers.onnx`.
+* Exportar un modelo personalizado para una arquitectura no compatible.
+
+### Exportar un model a ONNX
+
+Para exportar un modelo 🤗 Transformers a ONNX, tienes que instalar primero algunas
+dependencias extra:
+
+```bash
+pip install transformers[onnx]
+```
+
+El paquete `transformers.onnx` puede ser usado luego como un módulo de Python:
+
+```bash
+python -m transformers.onnx --help
+
+usage: Hugging Face Transformers ONNX exporter [-h] -m MODEL [--feature {causal-lm, ...}] [--opset OPSET] [--atol ATOL] output
+
+positional arguments:
+ output Path indicating where to store generated ONNX model.
+
+optional arguments:
+ -h, --help show this help message and exit
+ -m MODEL, --model MODEL
+ Model ID on huggingface.co or path on disk to load model from.
+ --feature {causal-lm, ...}
+ The type of features to export the model with.
+ --opset OPSET ONNX opset version to export the model with.
+ --atol ATOL Absolute difference tolerence when validating the model.
+```
+
+Exportar un checkpoint usando una configuración a la medida se puede hacer de la siguiente manera:
+
+```bash
+python -m transformers.onnx --model=distilbert/distilbert-base-uncased onnx/
+```
+
+que debería mostrar los siguientes registros:
+
+```bash
+Validating ONNX model...
+ -[✓] ONNX model output names match reference model ({'last_hidden_state'})
+ - Validating ONNX Model output "last_hidden_state":
+ -[✓] (2, 8, 768) matches (2, 8, 768)
+ -[✓] all values close (atol: 1e-05)
+All good, model saved at: onnx/model.onnx
+```
+
+Esto exporta un grafo ONNX del checkpoint definido por el argumento `--model`.
+En este ejemplo, es un modelo `distilbert/distilbert-base-uncased`, pero puede ser cualquier
+checkpoint en Hugging Face Hub o que esté almacenado localmente.
+
+El archivo `model.onnx` resultante se puede ejecutar en uno de los
+[muchos aceleradores](https://onnx.ai/supported-tools.html#deployModel)
+que admiten el estándar ONNX. Por ejemplo, podemos cargar y ejecutar el
+modelo con [ONNX Runtime](https://onnxruntime.ai/) de la siguiente manera:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> from onnxruntime import InferenceSession
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> session = InferenceSession("onnx/model.onnx")
+>>> # ONNX Runtime expects NumPy arrays as input
+>>> inputs = tokenizer("Using DistilBERT with ONNX Runtime!", return_tensors="np")
+>>> outputs = session.run(output_names=["last_hidden_state"], input_feed=dict(inputs))
+```
+
+Los nombres necesarios de salida (es decir, `["last_hidden_state"]`) se pueden obtener
+echando un vistazo a la configuración ONNX de cada modelo. Por ejemplo, para DistilBERT tenemos:
+
+```python
+>>> from transformers.models.distilbert import DistilBertConfig, DistilBertOnnxConfig
+
+>>> config = DistilBertConfig()
+>>> onnx_config = DistilBertOnnxConfig(config)
+>>> print(list(onnx_config.outputs.keys()))
+["last_hidden_state"]s
+```
+
+El proceso es idéntico para los checkpoints de TensorFlow en Hub.
+Por ejemplo, podemos exportar un checkpoint puro de TensorFlow desde
+[Keras](https://huggingface.co/keras-io) de la siguiente manera:
+
+```bash
+python -m transformers.onnx --model=keras-io/transformers-qa onnx/
+```
+
+Para exportar un modelo que está almacenado localmente, deberás tener los pesos
+y tokenizadores del modelo almacenados en un directorio. Por ejemplo, podemos cargar
+y guardar un checkpoint de la siguiente manera:
+
+
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> # Load tokenizer and PyTorch weights form the Hub
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+>>> # Save to disk
+>>> tokenizer.save_pretrained("local-pt-checkpoint")
+>>> pt_model.save_pretrained("local-pt-checkpoint")
+```
+
+Una vez que se guarda el checkpoint, podemos exportarlo a ONNX usando el argumento `--model`
+del paquete `transformers.onnx` al directorio deseado:
+
+```bash
+python -m transformers.onnx --model=local-pt-checkpoint onnx/
+```
+
+
+```python
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> # Load tokenizer and TensorFlow weights from the Hub
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+>>> # Save to disk
+>>> tokenizer.save_pretrained("local-tf-checkpoint")
+>>> tf_model.save_pretrained("local-tf-checkpoint")
+```
+
+Una vez que se guarda el checkpoint, podemos exportarlo a ONNX usando el argumento `--model`
+del paquete `transformers.onnx` al directorio deseado:
+
+```bash
+python -m transformers.onnx --model=local-tf-checkpoint onnx/
+```
+
+
+
+### Seleccionar características para diferentes topologías de un modelo
+
+Cada configuración a la medida viene con un conjunto de _características_ que te permiten exportar
+modelos para diferentes tipos de topologías o tareas. Como se muestra en la siguiente tabla, cada
+función está asociada con una auto-clase de automóvil diferente:
+
+| Feature | Auto Class |
+| ------------------------------------ | ------------------------------------ |
+| `causal-lm`, `causal-lm-with-past` | `AutoModelForCausalLM` |
+| `default`, `default-with-past` | `AutoModel` |
+| `masked-lm` | `AutoModelForMaskedLM` |
+| `question-answering` | `AutoModelForQuestionAnswering` |
+| `seq2seq-lm`, `seq2seq-lm-with-past` | `AutoModelForSeq2SeqLM` |
+| `sequence-classification` | `AutoModelForSequenceClassification` |
+| `token-classification` | `AutoModelForTokenClassification` |
+
+Para cada configuración, puedes encontrar la lista de funciones admitidas a través de `FeaturesManager`.
+Por ejemplo, para DistilBERT tenemos:
+
+```python
+>>> from transformers.onnx.features import FeaturesManager
+
+>>> distilbert_features = list(FeaturesManager.get_supported_features_for_model_type("distilbert").keys())
+>>> print(distilbert_features)
+["default", "masked-lm", "causal-lm", "sequence-classification", "token-classification", "question-answering"]
+```
+
+Le puedes pasar una de estas características al argumento `--feature` en el paquete `transformers.onnx`.
+Por ejemplo, para exportar un modelo de clasificación de texto, podemos elegir un modelo ya ajustado del Hub y ejecutar:
+
+```bash
+python -m transformers.onnx --model=distilbert/distilbert-base-uncased-finetuned-sst-2-english \
+ --feature=sequence-classification onnx/
+```
+
+que mostrará los siguientes registros:
+
+```bash
+Validating ONNX model...
+ -[✓] ONNX model output names match reference model ({'logits'})
+ - Validating ONNX Model output "logits":
+ -[✓] (2, 2) matches (2, 2)
+ -[✓] all values close (atol: 1e-05)
+All good, model saved at: onnx/model.onnx
+```
+
+Ten en cuenta que, en este caso, los nombres de salida del modelo ajustado son `logits` en lugar de `last_hidden_state`
+que vimos anteriormente con el checkpoint `distilbert/distilbert-base-uncased`. Esto es de esperarse ya que el modelo ajustado
+tiene un cabezal de clasificación secuencial.
+
+
+
+Las características que tienen un sufijo 'with-past' (por ejemplo, 'causal-lm-with-past') corresponden a topologías
+de modelo con estados ocultos precalculados (clave y valores en los bloques de atención) que se pueden usar para una
+decodificación autorregresiva más rápida.
+
+
+
+
+### Exportar un modelo para una arquitectura no compatible
+
+Si deseas exportar un modelo cuya arquitectura no es compatible de forma nativa
+con la biblioteca, debes seguir tres pasos principales:
+
+1. Implementa una configuración personalizada en ONNX.
+2. Exporta el modelo a ONNX.
+3. Valide los resultados de PyTorch y los modelos exportados.
+
+En esta sección, veremos cómo se implementó la serialización de DistilBERT
+para mostrar lo que implica cada paso.
+
+#### Implementar una configuración personalizada en ONNX
+
+Comencemos con el objeto de configuración de ONNX. Proporcionamos tres clases abstractas
+de las que debe heredar, según el tipo de arquitectura del modelo que quieras exportar:
+
+* Modelos basados en el _Encoder_ inherente de [`~onnx.config.OnnxConfig`]
+* Modelos basados en el _Decoder_ inherente de [`~onnx.config.OnnxConfigWithPast`]
+* Modelos _Encoder-decoder_ inherente de [`~onnx.config.OnnxSeq2SeqConfigWithPast`]
+
+
+
+Una buena manera de implementar una configuración personalizada en ONNX es observar la implementación
+existente en el archivo `configuration_.py` de una arquitectura similar.
+
+
+
+Dado que DistilBERT es un modelo de tipo _encoder_, su configuración se hereda de `OnnxConfig`:
+
+```python
+>>> from typing import Mapping, OrderedDict
+>>> from transformers.onnx import OnnxConfig
+
+
+>>> class DistilBertOnnxConfig(OnnxConfig):
+... @property
+... def inputs(self) -> Mapping[str, Mapping[int, str]]:
+... return OrderedDict(
+... [
+... ("input_ids", {0: "batch", 1: "sequence"}),
+... ("attention_mask", {0: "batch", 1: "sequence"}),
+... ]
+... )
+```
+
+Cada objeto de configuración debe implementar la propiedad `inputs` y devolver un mapeo,
+donde cada llave corresponde a una entrada esperada y cada valor indica el eje de esa entrada.
+Para DistilBERT, podemos ver que se requieren dos entradas: `input_ids` y `attention_mask`.
+Estas entradas tienen la misma forma de `(batch_size, sequence_length)`, es por lo que vemos
+los mismos ejes utilizados en la configuración.
+
+
+
+Observa que la propiedad `inputs` para `DistilBertOnnxConfig` devuelve un `OrderedDict`.
+Esto nos asegura que las entradas coincidan con su posición relativa dentro del método
+`PreTrainedModel.forward()` al rastrear el grafo. Recomendamos usar un `OrderedDict`
+para las propiedades `inputs` y `outputs` al implementar configuraciones ONNX personalizadas.
+
+
+
+Una vez que hayas implementado una configuración ONNX, puedes crear una
+instancia proporcionando la configuración del modelo base de la siguiente manera:
+
+```python
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased")
+>>> onnx_config = DistilBertOnnxConfig(config)
+```
+
+El objeto resultante tiene varias propiedades útiles. Por ejemplo, puedes ver el conjunto de operadores ONNX que se
+utilizará durante la exportación:
+
+```python
+>>> print(onnx_config.default_onnx_opset)
+11
+```
+
+También puedes ver los resultados asociados con el modelo de la siguiente manera:
+
+```python
+>>> print(onnx_config.outputs)
+OrderedDict([("last_hidden_state", {0: "batch", 1: "sequence"})])
+```
+
+Observa que la propiedad de salidas sigue la misma estructura que las entradas;
+devuelve un objecto `OrderedDict` de salidas nombradas y sus formas. La estructura
+de salida está vinculada a la elección de la función con la que se inicializa la configuración.
+Por defecto, la configuración de ONNX se inicializa con la función `default` que
+corresponde a exportar un modelo cargado con la clase `AutoModel`. Si quieres exportar
+una topología de modelo diferente, simplemente proporciona una característica diferente
+al argumento `task` cuando inicialices la configuración de ONNX. Por ejemplo, si quisiéramos
+exportar DistilBERT con un cabezal de clasificación de secuencias, podríamos usar:
+
+```python
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased")
+>>> onnx_config_for_seq_clf = DistilBertOnnxConfig(config, task="sequence-classification")
+>>> print(onnx_config_for_seq_clf.outputs)
+OrderedDict([('logits', {0: 'batch'})])
+```
+
+
+
+Todas las propiedades base y métodos asociados con [`~onnx.config.OnnxConfig`] y las
+otras clases de configuración se pueden sobreescribir si es necesario.
+Consulte [`BartOnnxConfig`] para ver un ejemplo avanzado.
+
+
+
+#### Exportar el modelo
+
+Una vez que hayas implementado la configuración de ONNX, el siguiente paso es exportar el modelo.
+Aquí podemos usar la función `export()` proporcionada por el paquete `transformers.onnx`.
+Esta función espera la configuración de ONNX, junto con el modelo base y el tokenizador,
+y la ruta para guardar el archivo exportado:
+
+```python
+>>> from pathlib import Path
+>>> from transformers.onnx import export
+>>> from transformers import AutoTokenizer, AutoModel
+
+>>> onnx_path = Path("model.onnx")
+>>> model_ckpt = "distilbert/distilbert-base-uncased"
+>>> base_model = AutoModel.from_pretrained(model_ckpt)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_ckpt)
+
+>>> onnx_inputs, onnx_outputs = export(tokenizer, base_model, onnx_config, onnx_config.default_onnx_opset, onnx_path)
+```
+
+Los objetos `onnx_inputs` y `onnx_outputs` devueltos por la función `export()`
+son listas de llaves definidas en las propiedades `inputs` y `outputs` de la configuración.
+Una vez exportado el modelo, puedes probar que el modelo está bien formado de la siguiente manera:
+
+```python
+>>> import onnx
+
+>>> onnx_model = onnx.load("model.onnx")
+>>> onnx.checker.check_model(onnx_model)
+```
+
+
+
+Si tu modelo tiene más de 2GB, verás que se crean muchos archivos adicionales durante la exportación.
+Esto es _esperado_ porque ONNX usa [Búferes de protocolo](https://developers.google.com/protocol-buffers/)
+para almacenar el modelo y éstos tienen un límite de tamaño de 2 GB. Consulta la
+[documentación de ONNX](https://github.com/onnx/onnx/blob/master/docs/ExternalData.md) para obtener
+instrucciones sobre cómo cargar modelos con datos externos.
+
+
+
+#### Validar los resultados del modelo
+
+El paso final es validar que los resultados del modelo base y exportado coincidan dentro
+de cierta tolerancia absoluta. Aquí podemos usar la función `validate_model_outputs()`
+proporcionada por el paquete `transformers.onnx` de la siguiente manera:
+
+```python
+>>> from transformers.onnx import validate_model_outputs
+
+>>> validate_model_outputs(
+... onnx_config, tokenizer, base_model, onnx_path, onnx_outputs, onnx_config.atol_for_validation
+... )
+```
+
+Esta función usa el método `OnnxConfig.generate_dummy_inputs()` para generar entradas para el modelo base
+y exportado, y la tolerancia absoluta se puede definir en la configuración. En general, encontramos una
+concordancia numérica en el rango de 1e-6 a 1e-4, aunque es probable que cualquier valor menor que 1e-3 esté bien.
+
+### Contribuir con una nueva configuración a 🤗 Transformers
+
+¡Estamos buscando expandir el conjunto de configuraciones a la medida para usar y agradecemos las contribuciones de la comunidad!
+Si deseas contribuir con su colaboración a la biblioteca, deberás:
+
+* Implementa la configuración de ONNX en el archivo `configuration_.py` correspondiente
+* Incluye la arquitectura del modelo y las características correspondientes en [`~onnx.features.FeatureManager`]
+* Agrega tu arquitectura de modelo a las pruebas en `test_onnx_v2.py`
+
+Revisa cómo fue la contribución para la [configuración de IBERT](https://github.com/huggingface/transformers/pull/14868/files)
+y así tener una idea de lo que necesito.
+
+## TorchScript
+
+
+
+Este es el comienzo de nuestros experimentos con TorchScript y todavía estamos explorando sus capacidades con modelos de
+tamaño de entrada variable. Es un tema de interés y profundizaremos nuestro análisis en las próximas
+versiones, con más ejemplos de código, una implementación más flexible y puntos de referencia que comparen códigos
+basados en Python con TorchScript compilado.
+
+
+
+Según la documentación de PyTorch: "TorchScript es una forma de crear modelos serializables y optimizables a partir del
+código de PyTorch". Los dos módulos de Pytorch [JIT y TRACE](https://pytorch.org/docs/stable/jit.html) permiten al
+desarrollador exportar su modelo para reutilizarlo en otros programas, como los programas C++ orientados a la eficiencia.
+
+Hemos proporcionado una interfaz que permite exportar modelos de 🤗 Transformers a TorchScript para que puedan reutilizarse
+en un entorno diferente al de un programa Python basado en PyTorch. Aquí explicamos cómo exportar y usar nuestros modelos
+usando TorchScript.
+
+Exportar un modelo requiere de dos cosas:
+
+- un pase hacia adelante con entradas ficticias.
+- instanciación del modelo con la indicador `torchscript`.
+
+Estas necesidades implican varias cosas con las que los desarrolladores deben tener cuidado. Éstas se detallan a continuación.
+
+### Indicador de TorchScript y pesos atados
+
+Este indicador es necesario porque la mayoría de los modelos de lenguaje en este repositorio tienen pesos vinculados entre su capa
+de `Embedding` y su capa de `Decoding`. TorchScript no permite la exportación de modelos que tengan pesos atados, por lo que es
+necesario desvincular y clonar los pesos previamente.
+
+Esto implica que los modelos instanciados con el indicador `torchscript` tienen su capa `Embedding` y `Decoding` separadas,
+lo que significa que no deben entrenarse más adelante. El entrenamiento desincronizaría las dos capas, lo que generaría
+resultados inesperados.
+
+Este no es el caso de los modelos que no tienen un cabezal de modelo de lenguaje, ya que no tienen pesos atados.
+Estos modelos se pueden exportar de forma segura sin el indicador `torchscript`.
+
+### Entradas ficticias y longitudes estándar
+
+Las entradas ficticias se utilizan para crear un modelo de pase hacia adelante. Mientras los valores de las entradas se
+propagan a través de las capas, PyTorch realiza un seguimiento de las diferentes operaciones ejecutadas en cada tensor.
+Estas operaciones registradas se utilizan luego para crear el "rastro" del modelo.
+
+El rastro se crea en relación con las dimensiones de las entradas. Por lo tanto, está limitado por las dimensiones de la
+entrada ficticia y no funcionará para ninguna otra longitud de secuencia o tamaño de lote. Al intentar con un tamaño diferente,
+un error como:
+
+`The expanded size of the tensor (3) must match the existing size (7) at non-singleton dimension 2`
+
+aparecerá. Por lo tanto, se recomienda rastrear el modelo con un tamaño de entrada ficticia al menos tan grande como la
+entrada más grande que se alimentará al modelo durante la inferencia. El _padding_ se puede realizar para completar los
+valores que faltan. Sin embargo, como el modelo se habrá rastreado con un tamaño de entrada grande, las dimensiones de
+las diferentes matrices también serán grandes, lo que dará como resultado más cálculos.
+
+Se recomienda tener cuidado con el número total de operaciones realizadas en cada entrada y seguir de cerca el rendimiento
+al exportar modelos de longitud de secuencia variable.
+
+### Usar TorchScript en Python
+
+A continuación se muestra un ejemplo que muestra cómo guardar, cargar modelos y cómo usar el rastreo para la inferencia.
+
+#### Guardando un modelo
+
+Este fragmento muestra cómo usar TorchScript para exportar un `BertModel`. Aquí, el `BertModel` se instancia de acuerdo
+con la clase `BertConfig` y luego se guarda en el disco con el nombre de archivo `traced_bert.pt`
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+
+enc = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+
+# Tokenizing input text
+text = "[CLS] Who was Jim Henson ? [SEP] Jim Henson was a puppeteer [SEP]"
+tokenized_text = enc.tokenize(text)
+
+# Masking one of the input tokens
+masked_index = 8
+tokenized_text[masked_index] = "[MASK]"
+indexed_tokens = enc.convert_tokens_to_ids(tokenized_text)
+segments_ids = [0, 0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1]
+
+# Creating a dummy input
+tokens_tensor = torch.tensor([indexed_tokens])
+segments_tensors = torch.tensor([segments_ids])
+dummy_input = [tokens_tensor, segments_tensors]
+
+# Initializing the model with the torchscript flag
+# Flag set to True even though it is not necessary as this model does not have an LM Head.
+config = BertConfig(
+ vocab_size_or_config_json_file=32000,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ torchscript=True,
+)
+
+# Instantiating the model
+model = BertModel(config)
+
+# The model needs to be in evaluation mode
+model.eval()
+
+# If you are instantiating the model with *from_pretrained* you can also easily set the TorchScript flag
+model = BertModel.from_pretrained("google-bert/bert-base-uncased", torchscript=True)
+
+# Creating the trace
+traced_model = torch.jit.trace(model, [tokens_tensor, segments_tensors])
+torch.jit.save(traced_model, "traced_bert.pt")
+```
+
+#### Cargar un modelo
+
+Este fragmento muestra cómo cargar el `BertModel` que se guardó previamente en el disco con el nombre `traced_bert.pt`.
+Estamos reutilizando el `dummy_input` previamente inicializado.
+
+```python
+loaded_model = torch.jit.load("traced_bert.pt")
+loaded_model.eval()
+
+all_encoder_layers, pooled_output = loaded_model(*dummy_input)
+```
+
+#### Usar un modelo rastreado para la inferencia
+
+Usar el modelo rastreado para la inferencia es tan simple como usar su método `__call__`:
+
+```python
+traced_model(tokens_tensor, segments_tensors)
+```
+
+### Implementar los modelos HuggingFace TorchScript en AWS mediante Neuron SDK
+
+AWS presentó la familia de instancias [Amazon EC2 Inf1](https://aws.amazon.com/ec2/instance-types/inf1/) para la inferencia
+de aprendizaje automático de bajo costo y alto rendimiento en la nube. Las instancias Inf1 funcionan con el chip AWS
+Inferentia, un acelerador de hardware personalizado, que se especializa en cargas de trabajo de inferencia de aprendizaje
+profundo. [AWS Neuron](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/#) es el kit de desarrollo para Inferentia
+que admite el rastreo y la optimización de modelos de transformers para su implementación en Inf1. El SDK de Neuron proporciona:
+
+
+1. API fácil de usar con una línea de cambio de código para rastrear y optimizar un modelo de TorchScript para la inferencia en la nube.
+2. Optimizaciones de rendimiento listas para usar con un [costo-rendimiento mejorado](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/benchmark/>)
+3. Soporte para modelos HuggingFace Transformers construidos con [PyTorch](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/bert_tutorial/tutorial_pretrained_bert.html)
+o [TensorFlow](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/tensorflow/huggingface_bert/huggingface_bert.html).
+
+#### Implicaciones
+
+Los modelos Transformers basados en la arquitectura
+[BERT (Representaciones de _Enconder_ bidireccional de Transformers)](https://huggingface.co/docs/transformers/main/model_doc/bert),
+o sus variantes, como [distilBERT](https://huggingface.co/docs/transformers/main/model_doc/distilbert) y
+[roBERTa](https://huggingface.co/docs/transformers/main/model_doc/roberta), se ejecutarán mejor en Inf1 para tareas no
+generativas, como la respuesta extractiva de preguntas, la clasificación de secuencias y la clasificación de tokens.
+Como alternativa, las tareas de generación de texto se pueden adaptar para ejecutarse en Inf1, según este
+[tutorial de AWS Neuron MarianMT](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/transformers-marianmt.html).
+Puedes encontrar más información sobre los modelos que están listos para usarse en Inferentia en la
+[sección _Model Architecture Fit_ de la documentación de Neuron](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/models/models-inferentia.html#models-inferentia).
+
+#### Dependencias
+
+Usar AWS Neuron para convertir modelos requiere las siguientes dependencias y entornos:
+
+* Un [entorno Neuron SDK](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/neuron-frameworks/pytorch-neuron/index.html#installation-guide),
+que viene preconfigurado en [AWS Deep Learning AMI](https://docs.aws.amazon.com/dlami/latest/devguide/tutorial-inferentia-launching.html).
+
+#### Convertir un modelo a AWS Neuron
+
+Con el mismo script usado en [Uso de TorchScript en Python](https://huggingface.co/docs/transformers/main/es/serialization#using-torchscript-in-python)
+para rastrear un "BertModel", puedes importar la extensión del _framework_ `torch.neuron` para acceder a los componentes
+del SDK de Neuron a través de una API de Python.
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+import torch.neuron
+```
+Y modificando la línea de código de rastreo de:
+
+```python
+torch.jit.trace(model, [tokens_tensor, segments_tensors])
+```
+
+con lo siguiente:
+
+```python
+torch.neuron.trace(model, [token_tensor, segments_tensors])
+```
+
+Este cambio permite a Neuron SDK rastrear el modelo y optimizarlo para ejecutarse en instancias Inf1.
+
+Para obtener más información sobre las funciones, las herramientas, los tutoriales de ejemplo y las últimas actualizaciones
+de AWS Neuron SDK, consulte la [documentación de AWS NeuronSDK](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/index.html).
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/task_summary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/task_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..639654c3697a2b85eabd5b3153efd841f5d69a61
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/task_summary.md
@@ -0,0 +1,340 @@
+
+
+# Lo que 🤗 Transformers puede hacer
+
+🤗 Transformers es una biblioteca de modelos preentrenados de última generación para procesamiento del lenguaje natural (NLP, por sus siglas en inglés), visión por computadora y tareas de procesamiento de audio y voz. No solo contiene modelos Transformer, sino también modelos no Transformer como redes convolucionales modernas para tareas de visión por computadora. Si observas algunos de los productos de consumo más populares hoy en día, como teléfonos inteligentes, aplicaciones y televisores, es probable que haya alguna tecnología de aprendizaje profundo detrás. ¿Quieres quitar un objeto de fondo de una foto tomada por tu teléfono inteligente? Este es un ejemplo de una tarea de segmentación panóptica (no te preocupes si aún no sabes qué significa, ¡lo describiremos en las siguientes secciones!).
+
+Esta página proporciona una descripción general de las diferentes tareas de procesamiento de audio y voz, visión por computadora y NLP que se pueden resolver con la biblioteca 🤗 Transformers en solo tres líneas de código.
+
+## Audio
+
+Las tareas de procesamiento de audio y voz son un poco diferentes de las otras modalidades principalmente porque el audio como entrada es una señal continua. A diferencia del texto, una forma de onda de audio cruda no se puede dividir ordenadamente en fragmentos discretos de la misma manera en que una oración puede dividirse en palabras. Para superar esto, la señal de audio cruda generalmente se muestrea a intervalos regulares. Si tomas más muestras dentro de un intervalo, la tasa de muestreo es mayor y el audio se asemeja más a la fuente de audio original.
+
+Enfoques anteriores preprocesaban el audio para extraer características útiles. Ahora es más común comenzar las tareas de procesamiento de audio y voz alimentando directamente la forma de onda de audio cruda a un codificador de características para extraer una representación de audio. Esto simplifica el paso de preprocesamiento y permite que el modelo aprenda las características más esenciales.
+
+### Clasificación de audio
+
+La clasificación de audio es una tarea que etiqueta datos de audio con un conjunto predefinido de clases. Es una categoría amplia con muchas aplicaciones específicas, algunas de las cuales incluyen:
+
+* clasificación de escena acústica: etiquetar audio con una etiqueta de escena ("oficina", "playa", "estadio")
+* detección de eventos acústicos: etiquetar audio con una etiqueta de evento de sonido ("bocina de automóvil", "llamada de ballena", "cristal rompiéndose")
+* etiquetado: etiquetar audio que contiene varios sonidos (canto de pájaros, identificación de altavoces en una reunión)
+* clasificación de música: etiquetar música con una etiqueta de género ("metal", "hip-hop", "country")
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="audio-classification", model="superb/hubert-base-superb-er")
+>>> preds = classifier("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4532, 'label': 'hap'},
+ {'score': 0.3622, 'label': 'sad'},
+ {'score': 0.0943, 'label': 'neu'},
+ {'score': 0.0903, 'label': 'ang'}]
+```
+
+### Reconocimiento automático del habla
+
+El reconocimiento automático del habla (ASR, por sus siglas en inglés) transcribe el habla a texto. Es una de las tareas de audio más comunes, en parte debido a que el habla es una forma natural de comunicación humana. Hoy en día, los sistemas ASR están integrados en productos de tecnología "inteligente" como altavoces, teléfonos y automóviles. Podemos pedirle a nuestros asistentes virtuales que reproduzcan música, establezcan recordatorios y nos informen sobre el clima.
+
+Pero uno de los desafíos clave que las arquitecturas Transformer han ayudado a superar es en los idiomas con recursos limitados. Al preentrenar con grandes cantidades de datos de habla, afinar el modelo solo con una hora de datos de habla etiquetados en un idioma con recursos limitados aún puede producir resultados de alta calidad en comparación con los sistemas ASR anteriores entrenados con 100 veces más datos etiquetados.
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline(task="automatic-speech-recognition", model="openai/whisper-small")
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+## Visión por computadora
+
+Una de las primeras y exitosas tareas de visión por computadora fue reconocer imágenes de números de código postal utilizando una [red neuronal convolucional](glossary#convolution) (CNN, por sus siglas en inglés). Una imagen está compuesta por píxeles, y cada píxel tiene un valor numérico. Esto facilita representar una imagen como una matriz de valores de píxeles. Cada combinación particular de valores de píxeles describe los colores de una imagen.
+
+Dos formas generales en las que se pueden resolver las tareas de visión por computadora son:
+
+1. Utilizar convoluciones para aprender las características jerárquicas de una imagen, desde características de bajo nivel hasta cosas abstractas de alto nivel.
+2. Dividir una imagen en parches y utilizar un Transformer para aprender gradualmente cómo cada parche de imagen se relaciona entre sí para formar una imagen. A diferencia del enfoque ascendente preferido por una CNN, esto es como comenzar con una imagen borrosa y luego enfocarla gradualmente.
+
+### Clasificación de imágenes
+
+La clasificación de imágenes etiqueta una imagen completa con un conjunto predefinido de clases. Como la mayoría de las tareas de clasificación, hay muchos casos prácticos para la clasificación de imágenes, algunos de los cuales incluyen:
+
+* salud: etiquetar imágenes médicas para detectar enfermedades o monitorear la salud del paciente
+* medio ambiente: etiquetar imágenes de satélite para monitorear la deforestación, informar la gestión de áreas silvestres o detectar incendios forestales
+* agricultura: etiquetar imágenes de cultivos para monitorear la salud de las plantas o imágenes de satélite para el monitoreo del uso del suelo
+* ecología: etiquetar imágenes de especies animales o vegetales para monitorear poblaciones de vida silvestre o rastrear especies en peligro de extinción
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="image-classification")
+>>> preds = classifier(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> print(*preds, sep="\n")
+{'score': 0.4335, 'label': 'lynx, catamount'}
+{'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}
+{'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}
+{'score': 0.0239, 'label': 'Egyptian cat'}
+{'score': 0.0229, 'label': 'tiger cat'}
+```
+
+### Detección de objetos
+
+A diferencia de la clasificación de imágenes, la detección de objetos identifica múltiples objetos dentro de una imagen y las posiciones de los objetos en la imagen (definidas por el cuadro delimitador). Algunas aplicaciones ejemplares de la detección de objetos incluyen:
+
+* vehículos autónomos: detectar objetos de tráfico cotidianos como otros vehículos, peatones y semáforos
+* teledetección: monitoreo de desastres, planificación urbana y pronóstico del tiempo
+* detección de defectos: detectar grietas o daños estructurales en edificios y defectos de fabricación
+
+```py
+>>> from transformers import pipeline
+
+>>> detector = pipeline(task="object-detection")
+>>> preds = detector(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"], "box": pred["box"]} for pred in preds]
+>>> preds
+[{'score': 0.9865,
+ 'label': 'cat',
+ 'box': {'xmin': 178, 'ymin': 154, 'xmax': 882, 'ymax': 598}}]
+```
+
+### Segmentación de imágenes
+
+La segmentación de imágenes es una tarea a nivel de píxeles que asigna cada píxel en una imagen a una clase. A diferencia de la detección de objetos, que utiliza cuadros delimitadores para etiquetar y predecir objetos en una imagen, la segmentación es más granular. La segmentación puede detectar objetos a nivel de píxeles. Hay varios tipos de segmentación de imágenes:
+
+* segmentación de instancias: además de etiquetar la clase de un objeto, también etiqueta cada instancia distinta de un objeto ("perro-1", "perro-2")
+* segmentación panóptica: una combinación de segmentación semántica y de instancias; etiqueta cada píxel con una clase semántica **y** cada instancia distinta de un objeto
+
+Las tareas de segmentación son útiles en vehículos autónomos para crear un mapa a nivel de píxeles del mundo que los rodea para que puedan navegar de manera segura alrededor de peatones y otros vehículos. También es útil en imágenes médicas, donde la mayor granularidad de la tarea puede ayudar a identificar células anormales o características de órganos. La segmentación de imágenes también se puede utilizar en comercio electrónico para probar virtualmente la ropa o crear experiencias de realidad aumentada superponiendo objetos en el mundo real a través de tu cámara.
+
+```py
+>>> from transformers import pipeline
+
+>>> segmenter = pipeline(task="image-segmentation")
+>>> preds = segmenter(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> print(*preds, sep="\n")
+{'score': 0.9879, 'label': 'LABEL_184'}
+{'score': 0.9973, 'label': 'snow'}
+{'score': 0.9972, 'label': 'cat'}
+```
+
+### Estimación de profundidad
+
+La estimación de profundidad predice la distancia de cada píxel en una imagen desde la cámara. Esta tarea de visión por computadora es especialmente importante para la comprensión y reconstrucción de escenas. Por ejemplo, en los vehículos autónomos, es necesario entender qué tan lejos están los objetos como peatones, señales de tráfico y otros vehículos para evitar obstáculos y colisiones. La información de profundidad también es útil para construir representaciones 3D a partir de imágenes 2D y se puede utilizar para crear representaciones 3D de alta calidad de estructuras biológicas o edificios.
+
+Hay dos enfoques para la estimación de profundidad:
+
+* estéreo: las profundidades se estiman comparando dos imágenes de la misma escena desde ángulos ligeramente diferentes
+* monocular: las profundidades se estiman a partir de una sola imagen
+
+```py
+>>> from transformers import pipeline
+
+>>> depth_estimator = pipeline(task="depth-estimation")
+>>> preds = depth_estimator(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+```
+
+## Procesamiento del lenguaje natural
+
+Las tareas de procesamiento del lenguaje natural (NLP, por sus siglas en inglés) están entre los tipos de tareas más comunes porque el texto es una forma natural de comunicación para nosotros. Para convertir el texto en un formato reconocido por un modelo, es necesario tokenizarlo. Esto significa dividir una secuencia de texto en palabras o subpalabras separadas (tokens) y luego convertir estos tokens en números. Como resultado, puedes representar una secuencia de texto como una secuencia de números, y una vez que tienes una secuencia de números, se puede ingresar a un modelo para resolver todo tipo de tareas de NLP.
+
+### Clasificación de texto
+
+Al igual que las tareas de clasificación en cualquier modalidad, la clasificación de texto etiqueta una secuencia de texto (puede ser a nivel de oración, párrafo o documento) de un conjunto predefinido de clases. Hay muchas aplicaciones prácticas para la clasificación de texto, algunas de las cuales incluyen:
+
+* análisis de sentimientos: etiquetar texto según alguna polaridad como `positivo` o `negativo`, lo que puede informar y respaldar la toma de decisiones en campos como política, finanzas y marketing
+* clasificación de contenido: etiquetar texto según algún tema para ayudar a organizar y filtrar información en noticias y feeds de redes sociales (`clima`, `deportes`, `finanzas`, etc.)
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="sentiment-analysis")
+>>> preds = classifier("Hugging Face is the best thing since sliced bread!")
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.9991, 'label': 'POSITIVE'}]
+```
+
+### Clasificación de tokens
+
+En cualquier tarea de NLP, el texto se procesa separando la secuencia de texto en palabras o subpalabras individuales. Estas se conocen como [tokens](glossary#token). La clasificación de tokens asigna a cada token una etiqueta de un conjunto predefinido de clases.
+
+Dos tipos comunes de clasificación de tokens son:
+
+* reconocimiento de entidades nombradas (NER, por sus siglas en inglés): etiquetar un token según una categoría de entidad como organización, persona, ubicación o fecha. NER es especialmente popular en entornos biomédicos, donde puede etiquetar genes, proteínas y nombres de medicamentos
+* etiquetado de partes del discurso (POS, por sus siglas en inglés): etiquetar un token según su parte del discurso, como sustantivo, verbo o adjetivo. POS es útil para ayudar a los sistemas de traducción a comprender cómo dos palabras idénticas son gramaticalmente diferentes (por ejemplo, "corte" como sustantivo versus "corte" como verbo)
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="ner")
+>>> preds = classifier("Hugging Face is a French company based in New York City.")
+>>> preds = [
+... {
+... "entity": pred["entity"],
+... "score": round(pred["score"], 4),
+... "index": pred["index"],
+... "word": pred["word"],
+... "start": pred["start"],
+... "end": pred["end"],
+... }
+... for pred in preds
+... ]
+>>> print(*preds, sep="\n")
+{'entity': 'I-ORG', 'score': 0.9968, 'index': 1, 'word': 'Hu', 'start': 0, 'end': 2}
+{'entity': 'I-ORG', 'score': 0.9293, 'index': 2, 'word': '##gging', 'start': 2, 'end': 7}
+{'entity': 'I-ORG', 'score': 0.9763, 'index': 3, 'word': 'Face', 'start': 8, 'end': 12}
+{'entity': 'I-MISC', 'score': 0.9983, 'index': 6, 'word': 'French', 'start': 18, 'end': 24}
+{'entity': 'I-LOC', 'score': 0.999, 'index': 10, 'word': 'New', 'start': 42, 'end': 45}
+{'entity': 'I-LOC', 'score': 0.9987, 'index': 11, 'word': 'York', 'start': 46, 'end': 50}
+{'entity': 'I-LOC', 'score': 0.9992, 'index': 12, 'word': 'City', 'start': 51, 'end': 55}
+```
+
+### Respuestas a preguntas
+
+Responder preguntas es otra tarea a nivel de tokens que devuelve una respuesta a una pregunta, a veces con contexto (dominio abierto) y otras veces sin contexto (dominio cerrado). Esta tarea ocurre cuando le preguntamos algo a un asistente virtual, como si un restaurante está abierto. También puede proporcionar soporte al cliente o técnico y ayudar a los motores de búsqueda a recuperar la información relevante que estás buscando.
+
+Hay dos tipos comunes de respuestas a preguntas:
+
+* extractivas: dada una pregunta y algún contexto, la respuesta es un fragmento de texto del contexto que el modelo debe extraer
+* abstractivas: dada una pregunta y algún contexto, la respuesta se genera a partir del contexto; este enfoque lo maneja la [`Text2TextGenerationPipeline`] en lugar del [`QuestionAnsweringPipeline`] que se muestra a continuación
+
+```py
+>>> from transformers import pipeline
+
+>>> question_answerer = pipeline(task="question-answering")
+>>> preds = question_answerer(
+... question="What is the name of the repository?",
+... context="The name of the repository is huggingface/transformers",
+... )
+>>> print(
+... f"score: {round(preds['score'], 4)}, start: {preds['start']}, end: {preds['end']}, answer: {preds['answer']}"
+... )
+score: 0.9327, start: 30, end: 54, answer: huggingface/transformers
+```
+
+### Resumir
+
+Al resumir se crea una versión más corta de un texto más largo mientras intenta preservar la mayor parte del significado del documento original. Resumir es una tarea de secuencia a secuencia; produce una secuencia de texto más corta que la entrada. Hay muchos documentos de formato largo que se pueden resumir para ayudar a los lectores a comprender rápidamente los puntos principales. Proyectos de ley legislativos, documentos legales y financieros, patentes y artículos científicos son algunos ejemplos de documentos que podrían resumirse para ahorrar tiempo a los lectores y servir como ayuda para la lectura.
+
+Al igual que en las respuestas a preguntas, hay dos tipos de resumen:
+
+* extractiva: identifica y extrae las oraciones más importantes del texto original
+* abstractiva: genera el resumen objetivo (que puede incluir nuevas palabras no presentes en el documento de entrada) a partir del texto original; el [`SummarizationPipeline`] utiliza el enfoque abstractivo
+
+```py
+>>> from transformers import pipeline
+
+>>> summarizer = pipeline(task="summarization")
+>>> summarizer(
+... "In this work, we presented the Transformer, the first sequence transduction model based entirely on attention, replacing the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention. For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers. On both WMT 2014 English-to-German and WMT 2014 English-to-French translation tasks, we achieve a new state of the art. In the former task our best model outperforms even all previously reported ensembles."
+... )
+[{'summary_text': ' The Transformer is the first sequence transduction model based entirely on attention . It replaces the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention . For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers .'}]
+```
+
+### Traducción
+
+La traducción convierte una secuencia de texto en un idioma a otro. Es importante para ayudar a personas de diferentes orígenes a comunicarse entre sí, traducir contenido para llegar a audiencias más amplias e incluso ser una herramienta de aprendizaje para ayudar a las personas a aprender un nuevo idioma. Al igual que resumir, la traducción es una tarea de secuencia a secuencia, lo que significa que el modelo recibe una secuencia de entrada y devuelve una secuencia de salida objetivo.
+
+En sus primeros días, los modelos de traducción eran principalmente monolingües, pero recientemente ha habido un creciente interés en modelos multilingües que pueden traducir entre muchas combinaciones de idiomas.
+
+```py
+>>> from transformers import pipeline
+
+>>> text = "translate English to French: Hugging Face is a community-based open-source platform for machine learning."
+>>> translator = pipeline(task="translation", model="t5-small")
+>>> translator(text)
+[{'translation_text': "Hugging Face est une tribune communautaire de l'apprentissage des machines."}]
+```
+
+### Modelado de lenguaje
+
+El modelado de lenguaje es una tarea que predice una palabra en una secuencia de texto. Se ha vuelto una tarea de NLP muy popular porque un modelo de lenguaje preentrenado puede ser afinado para muchas otras tareas secundarias. Últimamente, ha habido mucho interés en modelos de lenguaje grandes (LLM, por sus siglas en inglés) que demuestran aprendizaje de cero o con pocas muestras (zero- or few-shot learning). ¡Esto significa que el modelo puede resolver tareas para las cuales no fue entrenado explícitamente! Los modelos de lenguaje se pueden utilizar para generar texto fluido y convincente, aunque debes tener cuidado, ya que el texto no siempre puede ser preciso.
+
+Hay dos tipos de modelado de lenguaje:
+
+* causal: el objetivo del modelo es predecir el próximo token en una secuencia, y los tokens futuros están enmascarados
+
+ ```py
+ >>> from transformers import pipeline
+
+ >>> prompt = "Hugging Face is a community-based open-source platform for machine learning."
+ >>> generator = pipeline(task="text-generation")
+ >>> generator(prompt) # doctest: +SKIP
+ ```
+
+* enmascarado: el objetivo del modelo es predecir un token enmascarado en una secuencia con acceso completo a los tokens en la secuencia
+
+ ```py
+ >>> text = "Hugging Face is a community-based open-source for machine learning."
+ >>> fill_mask = pipeline(task="fill-mask")
+ >>> preds = fill_mask(text, top_k=1)
+ >>> preds = [
+ ... {
+ ... "score": round(pred["score"], 4),
+ ... "token": pred["token"],
+ ... "token_str": pred["token_str"],
+ ... "sequence": pred["sequence"],
+ ... }
+ ... for pred in preds
+ ... ]
+ >>> preds
+ [{'score': 0.2236,
+ 'token': 1761,
+ 'token_str': ' platform',
+ 'sequence': 'Hugging Face is a community-based open-source platform for machine learning.'}]
+ ```
+
+## Multimodal
+
+Las tareas multimodales requieren que un modelo procese múltiples modalidades de datos (texto, imagen, audio, video) para resolver un problema particular. La descripción de imágenes es un ejemplo de una tarea multimodal en la que el modelo toma una imagen como entrada y produce una secuencia de texto que describe la imagen o algunas propiedades de la imagen.
+
+Aunque los modelos multimodales trabajan con diferentes tipos de datos o modalidades, internamente, los pasos de preprocesamiento ayudan al modelo a convertir todos los tipos de datos en embeddings (vectores o listas de números que contienen información significativa sobre los datos). Para una tarea como la descripción de imágenes, el modelo aprende las relaciones entre los embeddings de imágenes y los embeddings de texto.
+
+### Respuestas a preguntas de documentos
+
+Las respuestas a preguntas de documentos es una tarea que responde preguntas en lenguaje natural a partir de un documento. A diferencia de una tarea de respuestas a preguntas a nivel de token que toma texto como entrada, las respuestas a preguntas de documentos toman una imagen de un documento como entrada junto con una pregunta sobre el documento y devuelven una respuesta. Las respuestas a preguntas de documentos pueden usarse para analizar documentos estructurados y extraer información clave de ellos. En el ejemplo a continuación, el monto total y el cambio debido se pueden extraer de un recibo.
+
+```py
+>>> from transformers import pipeline
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "https://huggingface.co/datasets/hf-internal-testing/example-documents/resolve/main/jpeg_images/2.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> doc_question_answerer = pipeline("document-question-answering", model="magorshunov/layoutlm-invoices")
+>>> preds = doc_question_answerer(
+... question="What is the total amount?",
+... image=image,
+... )
+>>> preds
+[{'score': 0.8531, 'answer': '17,000', 'start': 4, 'end': 4}]
+```
+
+Con suerte, esta página te ha proporcionado más información de fondo sobre todos los tipos de tareas en cada modalidad y la importancia práctica de cada una. En la próxima [sección](tasks_explained), aprenderás **cómo** 🤗 Transformers trabaja para resolver estas tareas.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/asr.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/asr.md
new file mode 100644
index 0000000000000000000000000000000000000000..41e9f82e35f7f1932e729b8224f1d89fbb5f4d72
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/asr.md
@@ -0,0 +1,366 @@
+
+
+# Reconocimiento automático del habla
+
+
+
+Revisa la [página de la tarea](https://huggingface.co/tasks/automatic-speech-recognition) de reconocimiento automático del habla para acceder a más información sobre los modelos, datasets y métricas asociados.
+
+
+
+Antes de comenzar, asegúrate de haber instalado todas las librerías necesarias:
+
+```bash
+pip install transformers datasets evaluate jiwer
+```
+
+Te aconsejamos iniciar sesión con tu cuenta de Hugging Face para que puedas subir tu modelo y comartirlo con la comunidad. Cuando te sea solicitado, ingresa tu token para iniciar sesión:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Cargar el dataset MInDS-14
+
+Comencemos cargando un subconjunto más pequeño del dataset [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) desde la biblioteca 🤗 Datasets. De esta forma, tendrás la oportunidad de experimentar y asegurarte de que todo funcione antes de invertir más tiempo entrenando con el dataset entero.
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> minds = load_dataset("PolyAI/minds14", name="en-US", split="train[:100]")
+```
+Divide la partición `train` (entrenamiento) en una partición de entrenamiento y una de prueba usando el método [`~Dataset.train_test_split`]:
+
+```py
+>>> minds = minds.train_test_split(test_size=0.2)
+```
+
+Ahora échale un vistazo al dataset:
+
+```py
+>>> minds
+DatasetDict({
+ train: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 16
+ })
+ test: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 4
+ })
+})
+```
+
+Aunque el dataset contiene mucha información útil, como los campos `lang_id` (identificador del lenguaje) y `english_transcription` (transcripción al inglés), en esta guía nos enfocaremos en los campos `audio` y `transcription`. Puedes quitar las otras columnas con el método [`~datasets.Dataset.remove_columns`]:
+
+```py
+>>> minds = minds.remove_columns(["english_transcription", "intent_class", "lang_id"])
+```
+
+Vuelve a echarle un vistazo al ejemplo:
+
+```py
+>>> minds["train"][0]
+{'audio': {'array': array([-0.00024414, 0. , 0. , ..., 0.00024414,
+ 0.00024414, 0.00024414], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'sampling_rate': 8000},
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
+```
+
+Hay dos campos:
+
+- `audio`: un `array` (arreglo) unidimensional de la señal de habla que debe ser invocado para cargar y re-muestrear el archivo de audio.
+- `transcription`: el texto objetivo.
+
+## Preprocesamiento
+
+El siguiente paso es cargar un procesador Wav2Vec2 para procesar la señal de audio:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base")
+```
+El dataset MInDS-14 tiene una tasa de muestreo de 8000kHz (puedes encontrar esta información en su [tarjeta de dataset](https://huggingface.co/datasets/PolyAI/minds14)), lo que significa que tendrás que re-muestrear el dataset a 16000kHz para poder usar el modelo Wav2Vec2 pre-entrenado:
+
+```py
+>>> minds = minds.cast_column("audio", Audio(sampling_rate=16_000))
+>>> minds["train"][0]
+{'audio': {'array': array([-2.38064706e-04, -1.58618059e-04, -5.43987835e-06, ...,
+ 2.78103951e-04, 2.38446111e-04, 1.18740834e-04], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'sampling_rate': 16000},
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
+```
+
+Como puedes ver en el campo `transcription`, el texto contiene una mezcla de carácteres en mayúsculas y en minúsculas. El tokenizer Wav2Vec2 fue entrenado únicamente con carácteres en mayúsculas, así que tendrás que asegurarte de que el texto se ajuste al vocabulario del tokenizer:
+
+```py
+>>> def uppercase(example):
+... return {"transcription": example["transcription"].upper()}
+
+
+>>> minds = minds.map(uppercase)
+```
+
+Ahora vamos a crear una función de preprocesamiento que:
+
+1. Invoque la columna `audio` para cargar y re-muestrear el archivo de audio.
+2. Extraiga el campo `input_values` (valores de entrada) del archivo de audio y haga la tokenización de la columna `transcription` con el procesador.
+
+```py
+>>> def prepare_dataset(batch):
+... audio = batch["audio"]
+... batch = processor(audio["array"], sampling_rate=audio["sampling_rate"], text=batch["transcription"])
+... batch["input_length"] = len(batch["input_values"][0])
+... return batch
+```
+
+Para aplicar la función de preprocesamiento a todo el dataset, puedes usar la función [`~datasets.Dataset.map`] de 🤗 Datasets. Para acelerar la función `map` puedes incrementar el número de procesos con el parámetro `num_proc`. Quita las columnas que no necesites con el método [`~datasets.Dataset.remove_columns`]:
+
+```py
+>>> encoded_minds = minds.map(prepare_dataset, remove_columns=minds.column_names["train"], num_proc=4)
+```
+
+🤗 Transformers no tiene un collator de datos para la tarea de ASR, así que tendrás que adaptar el [`DataCollatorWithPadding`] para crear un lote de ejemplos. El collator también le aplicará padding dinámico a tu texto y etiquetas para que tengan la longitud del elemento más largo en su lote (en vez de la mayor longitud en el dataset entero), de forma que todas las muestras tengan una longitud uniforme. Aunque es posible hacerle padding a tu texto con el `tokenizer` haciendo `padding=True`, el padding dinámico es más eficiente.
+
+A diferencia de otros collators de datos, este tiene que aplicarle un método de padding distinto a los campos `input_values` (valores de entrada) y `labels` (etiquetas):
+
+```py
+>>> import torch
+
+>>> from dataclasses import dataclass, field
+>>> from typing import Any, Dict, List, Optional, Union
+
+
+>>> @dataclass
+... class DataCollatorCTCWithPadding:
+... processor: AutoProcessor
+... padding: Union[bool, str] = "longest"
+
+... def __call__(self, features: List[Dict[str, Union[List[int], torch.Tensor]]]) -> Dict[str, torch.Tensor]:
+... # particiona las entradas y las etiquetas ya que tienen que tener longitudes distintas y
+... # requieren métodos de padding diferentes
+... input_features = [{"input_values": feature["input_values"][0]} for feature in features]
+... label_features = [{"input_ids": feature["labels"]} for feature in features]
+
+... batch = self.processor.pad(input_features, padding=self.padding, return_tensors="pt")
+
+... labels_batch = self.processor.pad(labels=label_features, padding=self.padding, return_tensors="pt")
+
+... # remplaza el padding con -100 para ignorar la pérdida de forma correcta
+... labels = labels_batch["input_ids"].masked_fill(labels_batch.attention_mask.ne(1), -100)
+
+... batch["labels"] = labels
+
+... return batch
+```
+
+Ahora puedes instanciar tu `DataCollatorForCTCWithPadding`:
+
+```py
+>>> data_collator = DataCollatorCTCWithPadding(processor=processor, padding="longest")
+```
+
+## Evaluación
+
+A menudo es útil incluir una métrica durante el entrenamiento para evaluar el rendimiento de tu modelo. Puedes cargar un método de evaluación rápidamente con la biblioteca 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index). Para esta tarea, puedes usar la métrica de [tasa de error por palabra](https://huggingface.co/spaces/evaluate-metric/wer) (WER, por sus siglas en inglés). Puedes ver la [guía rápida](https://huggingface.co/docs/evaluate/a_quick_tour) de 🤗 Evaluate para aprender más acerca de cómo cargar y computar una métrica.
+
+```py
+>>> import evaluate
+
+>>> wer = evaluate.load("wer")
+```
+
+Ahora crea una función que le pase tus predicciones y etiquetas a [`~evaluate.EvaluationModule.compute`] para calcular la WER:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(pred):
+... pred_logits = pred.predictions
+... pred_ids = np.argmax(pred_logits, axis=-1)
+
+... pred.label_ids[pred.label_ids == -100] = processor.tokenizer.pad_token_id
+
+... pred_str = processor.batch_decode(pred_ids)
+... label_str = processor.batch_decode(pred.label_ids, group_tokens=False)
+
+... wer = wer.compute(predictions=pred_str, references=label_str)
+
+... return {"wer": wer}
+```
+
+Ahora tu función `compute_metrics` (computar métricas) está lista y podrás usarla cuando estés preparando tu entrenamiento.
+
+## Entrenamiento
+
+
+
+
+
+Si no tienes experiencia haciéndole fine-tuning a un modelo con el [`Trainer`], ¡échale un vistazo al tutorial básico [aquí](../training#train-with-pytorch-trainer)!
+
+
+
+¡Ya puedes empezar a entrenar tu modelo! Para ello, carga Wav2Vec2 con [`AutoModelForCTC`]. Especifica la reducción que quieres aplicar con el parámetro `ctc_loss_reduction`. A menudo, es mejor usar el promedio en lugar de la sumatoria que se hace por defecto.
+
+```py
+>>> from transformers import AutoModelForCTC, TrainingArguments, Trainer
+
+>>> model = AutoModelForCTC.from_pretrained(
+... "facebook/wav2vec2-base",
+... ctc_loss_reduction="mean",
+... pad_token_id=processor.tokenizer.pad_token_id,
+... )
+```
+En este punto, solo quedan tres pasos:
+
+1. Define tus hiperparámetros de entrenamiento en [`TrainingArguments`]. El único parámetro obligatorio es `output_dir` (carpeta de salida), el cual especifica dónde guardar tu modelo. Puedes subir este modelo al Hub haciendo `push_to_hub=True` (debes haber iniciado sesión en Hugging Face para subir tu modelo). Al final de cada época, el [`Trainer`] evaluará la WER y guardará el punto de control del entrenamiento.
+2. Pásale los argumentos del entrenamiento al [`Trainer`] junto con el modelo, el dataset, el tokenizer, el collator de datos y la función `compute_metrics`.
+3. Llama el método [`~Trainer.train`] para hacerle fine-tuning a tu modelo.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_asr_mind_model",
+... per_device_train_batch_size=8,
+... gradient_accumulation_steps=2,
+... learning_rate=1e-5,
+... warmup_steps=500,
+... max_steps=2000,
+... gradient_checkpointing=True,
+... fp16=True,
+... group_by_length=True,
+... eval_strategy="steps",
+... per_device_eval_batch_size=8,
+... save_steps=1000,
+... eval_steps=1000,
+... logging_steps=25,
+... load_best_model_at_end=True,
+... metric_for_best_model="wer",
+... greater_is_better=False,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=encoded_minds["train"],
+... eval_dataset=encoded_minds["test"],
+... processing_class=processor.feature_extractor,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+Una vez que el entrenamiento haya sido completado, comparte tu modelo en el Hub con el método [`~transformers.Trainer.push_to_hub`] para que todo el mundo pueda usar tu modelo:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+Para ver un ejemplo más detallado de cómo hacerle fine-tuning a un modelo para reconocimiento automático del habla, échale un vistazo a esta [entrada de blog](https://huggingface.co/blog/fine-tune-wav2vec2-english) para ASR en inglés y a esta [entrada](https://huggingface.co/blog/fine-tune-xlsr-wav2vec2) para ASR multilingüe.
+
+
+
+## Inferencia
+
+¡Genial, ahora que le has hecho fine-tuning a un modelo, puedes usarlo para inferencia!
+
+Carga el archivo de audio sobre el cual quieras correr la inferencia. ¡Recuerda re-muestrar la tasa de muestreo del archivo de audio para que sea la misma del modelo si es necesario!
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", "en-US", split="train")
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+>>> sampling_rate = dataset.features["audio"].sampling_rate
+>>> audio_file = dataset[0]["audio"]["path"]
+```
+
+La manera más simple de probar tu modelo para hacer inferencia es usarlo en un [`pipeline`]. Puedes instanciar un `pipeline` para reconocimiento automático del habla con tu modelo y pasarle tu archivo de audio:
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline("automatic-speech-recognition", model="stevhliu/my_awesome_asr_minds_model")
+>>> transcriber(audio_file)
+{'text': 'I WOUD LIKE O SET UP JOINT ACOUNT WTH Y PARTNER'}
+```
+
+
+
+La transcripción es decente, pero podría ser mejor. ¡Intenta hacerle fine-tuning a tu modelo con más ejemplos para obtener resultados aún mejores!
+
+
+
+También puedes replicar de forma manual los resultados del `pipeline` si lo deseas:
+
+
+
+Carga un procesador para preprocesar el archivo de audio y la transcripción y devuelve el `input` como un tensor de PyTorch:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("stevhliu/my_awesome_asr_mind_model")
+>>> inputs = processor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+```
+
+Pásale tus entradas al modelo y devuelve los logits:
+
+```py
+>>> from transformers import AutoModelForCTC
+
+>>> model = AutoModelForCTC.from_pretrained("stevhliu/my_awesome_asr_mind_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+Obtén los identificadores de los tokens con mayor probabilidad en las predicciones y usa el procesador para decodificarlos y transformarlos en texto:
+
+```py
+>>> import torch
+
+>>> predicted_ids = torch.argmax(logits, dim=-1)
+>>> transcription = processor.batch_decode(predicted_ids)
+>>> transcription
+['I WOUL LIKE O SET UP JOINT ACOUNT WTH Y PARTNER']
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/image_captioning.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/image_captioning.md
new file mode 100644
index 0000000000000000000000000000000000000000..620dcec1bfbd1c719f6e3f0929015a60aa240fa4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/image_captioning.md
@@ -0,0 +1,266 @@
+
+
+# Subtítulos de Imágenes
+
+[[open-in-colab]]
+
+Los subtítulos de imágenes es la tarea de predecir un subtítulo para una imagen dada. Las aplicaciones comunes en el mundo real incluyen
+ayudar a personas con discapacidad visual que les puede ayudar a navegar a través de diferentes situaciones. Por lo tanto, los subtítulos de imágenes
+ayuda a mejorar la accesibilidad del contenido para las personas describiéndoles imágenes.
+
+Esta guía te mostrará cómo:
+
+* Ajustar un modelo de subtítulos de imágenes.
+* Usar el modelo ajustado para inferencia.
+
+Antes de comenzar, asegúrate de tener todas las bibliotecas necesarias instaladas:
+
+```bash
+pip install transformers datasets evaluate -q
+pip install jiwer -q
+```
+
+Te animamos a que inicies sesión en tu cuenta de Hugging Face para que puedas subir y compartir tu modelo con la comunidad. Cuando se te solicite, ingresa tu token para iniciar sesión:
+
+```python
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+## Cargar el conjunto de datos de subtítulos BLIP de Pokémon
+
+Utiliza la biblioteca 🤗 Dataset para cargar un conjunto de datos que consiste en pares {image-caption}. Para crear tu propio conjunto de datos de subtítulos de imágenes
+en PyTorch, puedes seguir [este cuaderno](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/GIT/Fine_tune_GIT_on_an_image_captioning_dataset.ipynb).
+
+```python
+from datasets import load_dataset
+
+ds = load_dataset("lambdalabs/pokemon-blip-captions")
+ds
+```
+```bash
+DatasetDict({
+ train: Dataset({
+ features: ['image', 'text'],
+ num_rows: 833
+ })
+})
+```
+
+El conjunto de datos tiene dos características, `image` y `text`.
+
+
+
+Muchos conjuntos de datos de subtítulos de imágenes contienen múltiples subtítulos por imagen. En esos casos, una estrategia común es muestrear aleatoriamente un subtítulo entre los disponibles durante el entrenamiento.
+
+
+
+Divide el conjunto de entrenamiento del conjunto de datos en un conjunto de entrenamiento y de prueba con el método [`~datasets.Dataset.train_test_split`]:
+
+```python
+ds = ds["train"].train_test_split(test_size=0.1)
+train_ds = ds["train"]
+test_ds = ds["test"]
+```
+
+Vamos a visualizar un par de muestras del conjunto de entrenamiento.
+
+```python
+from textwrap import wrap
+import matplotlib.pyplot as plt
+import numpy as np
+
+
+def plot_images(images, captions):
+ plt.figure(figsize=(20, 20))
+ for i in range(len(images)):
+ ax = plt.subplot(1, len(images), i + 1)
+ caption = captions[i]
+ caption = "\n".join(wrap(caption, 12))
+ plt.title(caption)
+ plt.imshow(images[i])
+ plt.axis("off")
+
+
+sample_images_to_visualize = [np.array(train_ds[i]["image"]) for i in range(5)]
+sample_captions = [train_ds[i]["text"] for i in range(5)]
+plot_images(sample_images_to_visualize, sample_captions)
+```
+
+
+
+
+
+
+
+Consulta la [página de la tarea](https://huggingface.co/tasks/audio-classification) de clasificación de imágenes para obtener más información sobre sus modelos, datasets y métricas asociadas.
+
+
+
+## Carga el dataset Food-101
+
+Carga solo las primeras 5000 imágenes del dataset Food-101 de la biblioteca 🤗 de Datasets ya que es bastante grande:
+
+```py
+>>> from datasets import load_dataset
+
+>>> food = load_dataset("food101", split="train[:5000]")
+```
+
+Divide el dataset en un train y un test set:
+
+```py
+>>> food = food.train_test_split(test_size=0.2)
+```
+
+A continuación, observa un ejemplo:
+
+```py
+>>> food["train"][0]
+{'image': ,
+ 'label': 79}
+```
+
+El campo `image` contiene una imagen PIL, y cada `label` es un número entero que representa una clase. Crea un diccionario que asigne un nombre de label a un entero y viceversa. El mapeo ayudará al modelo a recuperar el nombre de label a partir del número de la misma:
+
+```py
+>>> labels = food["train"].features["label"].names
+>>> label2id, id2label = dict(), dict()
+>>> for i, label in enumerate(labels):
+... label2id[label] = str(i)
+... id2label[str(i)] = label
+```
+
+Ahora puedes convertir el número de label en un nombre de label para obtener más información:
+
+```py
+>>> id2label[str(79)]
+'prime_rib'
+```
+
+Cada clase de alimento - o label - corresponde a un número; `79` indica una costilla de primera en el ejemplo anterior.
+
+## Preprocesa
+
+Carga el image processor de ViT para procesar la imagen en un tensor:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224-in21k")
+```
+
+Aplica varias transformaciones de imagen al dataset para hacer el modelo más robusto contra el overfitting. En este caso se utilizará el módulo [`transforms`](https://pytorch.org/vision/stable/transforms.html) de torchvision. Recorta una parte aleatoria de la imagen, cambia su tamaño y normalízala con la media y la desviación estándar de la imagen:
+
+```py
+>>> from torchvision.transforms import RandomResizedCrop, Compose, Normalize, ToTensor
+
+>>> normalize = Normalize(mean=image_processor.image_mean, std=image_processor.image_std)
+>>> _transforms = Compose([RandomResizedCrop(image_processor.size["height"]), ToTensor(), normalize])
+```
+
+Crea una función de preprocesamiento que aplique las transformaciones y devuelva los `pixel_values` - los inputs al modelo - de la imagen:
+
+```py
+>>> def transforms(examples):
+... examples["pixel_values"] = [_transforms(img.convert("RGB")) for img in examples["image"]]
+... del examples["image"]
+... return examples
+```
+
+Utiliza el método [`with_transform`](https://huggingface.co/docs/datasets/package_reference/main_classes?#datasets.Dataset.with_transform) de 🤗 Dataset para aplicar las transformaciones sobre todo el dataset. Las transformaciones se aplican sobre la marcha cuando se carga un elemento del dataset:
+
+```py
+>>> food = food.with_transform(transforms)
+```
+
+Utiliza [`DefaultDataCollator`] para crear un batch de ejemplos. A diferencia de otros data collators en 🤗 Transformers, el DefaultDataCollator no aplica un preprocesamiento adicional como el padding.
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+## Entrena
+Carga ViT con [`AutoModelForImageClassification`]. Especifica el número de labels, y pasa al modelo el mapping entre el número de label y la clase de label:
+
+```py
+>>> from transformers import AutoModelForImageClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForImageClassification.from_pretrained(
+... "google/vit-base-patch16-224-in21k",
+... num_labels=len(labels),
+... id2label=id2label,
+... label2id=label2id,
+... )
+```
+
+
+
+Si no estás familiarizado con el fine-tuning de un modelo con el [`Trainer`], echa un vistazo al tutorial básico [aquí](../training#finetune-with-trainer)!
+
+
+
+Al llegar a este punto, solo quedan tres pasos:
+
+1. Define tus hiperparámetros de entrenamiento en [`TrainingArguments`]. Es importante que no elimines las columnas que no se utilicen, ya que esto hará que desaparezca la columna `image`. Sin la columna `image` no puedes crear `pixel_values`. Establece `remove_unused_columns=False` para evitar este comportamiento.
+2. Pasa los training arguments al [`Trainer`] junto con el modelo, los datasets, tokenizer y data collator.
+3. Llama [`~Trainer.train`] para hacer fine-tune de tu modelo.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="./results",
+... per_device_train_batch_size=16,
+... eval_strategy="steps",
+... num_train_epochs=4,
+... fp16=True,
+... save_steps=100,
+... eval_steps=100,
+... logging_steps=10,
+... learning_rate=2e-4,
+... save_total_limit=2,
+... remove_unused_columns=False,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... data_collator=data_collator,
+... train_dataset=food["train"],
+... eval_dataset=food["test"],
+... processing_class=image_processor,
+... )
+
+>>> trainer.train()
+```
+
+
+
+Para ver un ejemplo más a profundidad de cómo hacer fine-tune a un modelo para clasificación de imágenes, echa un vistazo al correspondiente [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/language_modeling.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/language_modeling.md
new file mode 100644
index 0000000000000000000000000000000000000000..9516876a00633e238f91507413acd0b4e6b5387a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/language_modeling.md
@@ -0,0 +1,421 @@
+
+
+# Modelado de lenguaje
+
+El modelado de lenguaje predice palabras en un enunciado. Hay dos formas de modelado de lenguaje.
+
+
+
+Mira la [página de tarea](https://huggingface.co/tasks/text-generation) para generación de texto y la [página de tarea](https://huggingface.co/tasks/fill-mask) para modelos de lenguajes por enmascaramiento para obtener más información sobre los modelos, datasets, y métricas asociadas.
+
+
+
+## Carga el dataset ELI5
+
+Carga solo los primeros 5000 registros desde la biblioteca 🤗 Datasets, dado que es bastante grande:
+
+```py
+>>> from datasets import load_dataset
+
+>>> eli5 = load_dataset("eli5", split="train_asks[:5000]")
+```
+
+Divide este dataset en subdatasets para el entrenamiento y el test:
+
+```py
+eli5 = eli5.train_test_split(test_size=0.2)
+```
+
+Luego observa un ejemplo:
+
+```py
+>>> eli5["train"][0]
+{'answers': {'a_id': ['c3d1aib', 'c3d4lya'],
+ 'score': [6, 3],
+ 'text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
+ "Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"]},
+ 'answers_urls': {'url': []},
+ 'document': '',
+ 'q_id': 'nyxfp',
+ 'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
+ 'selftext_urls': {'url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg']},
+ 'subreddit': 'askscience',
+ 'title': 'Few questions about this space walk photograph.',
+ 'title_urls': {'url': []}}
+```
+
+Observa que `text` es un subcampo anidado dentro del diccionario `answers`. Cuando preproceses el dataset, deberás extraer el subcampo `text` en una columna aparte.
+
+## Preprocesamiento
+
+
+
+Puedes usar el token de final de secuencia como el token de relleno y asignar `mlm=False`. Esto usará los inputs como etiquetas movidas un elemento hacia la derecha:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> tokenizer.pad_token = tokenizer.eos_token
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False)
+```
+
+Para modelados de lenguaje por enmascaramiento usa el mismo [`DataCollatorForLanguageModeling`] excepto que deberás especificar `mlm_probability` para enmascarar tokens aleatoriamente cada vez que iteras sobre los datos.
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> tokenizer.pad_token = tokenizer.eos_token
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=0.15)
+```
+
+
+Puedes usar el token de final de secuencia como el token de relleno y asignar `mlm=False`. Esto usará los inputs como etiquetas movidas un elemento hacia la derecha:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False, return_tensors="tf")
+```
+
+Para modelados de lenguajes por enmascaramiento usa el mismo [`DataCollatorForLanguageModeling`] excepto que deberás especificar `mlm_probability` para enmascarar tokens aleatoriamente cada vez que iteras sobre los datos.
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False, return_tensors="tf")
+```
+
+
+
+## Modelado de lenguaje causal
+
+El modelado de lenguaje causal es frecuentemente utilizado para generación de texto. Esta sección te muestra cómo realizar fine-tuning a [DistilGPT2](https://huggingface.co/distilbert/distilgpt2) para generar nuevo texto.
+
+### Entrenamiento
+
+
+
+Carga DistilGPT2 con [`AutoModelForCausalLM`]:
+
+```py
+>>> from transformers import AutoModelForCausalLM, TrainingArguments, Trainer
+
+>>> model = AutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+
+
+Si no estás familiarizado con el proceso de realizar fine-tuning sobre un modelo con [`Trainer`], considera el tutorial básico [aquí](../training#finetune-with-trainer)!
+
+
+
+A este punto, solo faltan tres pasos:
+
+1. Definir tus hiperparámetros de entrenamiento en [`TrainingArguments`].
+2. Pasarle los argumentos de entrenamiento a [`Trainer`] junto con el modelo, dataset, y el data collator.
+3. Realiza la llamada [`~Trainer.train`] para realizar el fine-tuning sobre tu modelo.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="./results",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... weight_decay=0.01,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=lm_dataset["train"],
+... eval_dataset=lm_dataset["test"],
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+
+Para realizar el fine-tuning de un modelo en TensorFlow, comienza por convertir tus datasets al formato `tf.data.Dataset` con [`to_tf_dataset`](https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.to_tf_dataset). Especifica los inputs y etiquetas en `columns`, ya sea para mezclar el dataset, tamaño de lote, y el data collator:
+
+```py
+>>> tf_train_set = lm_dataset["train"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "labels"],
+... dummy_labels=True,
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = lm_dataset["test"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "labels"],
+... dummy_labels=True,
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+
+
+Si no estás familiarizado con realizar fine-tuning de tus modelos con Keras, considera el tutorial básico [aquí](training#finetune-with-keras)!
+
+
+
+Crea la función optimizadora, la tasa de aprendizaje, y algunos hiperparámetros de entrenamiento:
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+Carga DistilGPT2 con [`TFAutoModelForCausalLM`]:
+
+```py
+>>> from transformers import TFAutoModelForCausalLM
+
+>>> model = TFAutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+Configura el modelo para entrenamiento con [`compile`](https://keras.io/api/models/model_training_apis/#compile-method):
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+Llama a [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) para realizar el fine-tuning del modelo:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3)
+```
+
+
+
+## Modelado de lenguaje por enmascaramiento
+
+El modelado de lenguaje por enmascaramiento es también conocido como una tarea de rellenar la máscara, pues predice un token enmascarado dada una secuencia. Los modelos de lenguaje por enmascaramiento requieren una buena comprensión del contexto de una secuencia entera, en lugar de solo el contexto a la izquierda. Esta sección te enseña como realizar el fine-tuning de [DistilRoBERTa](https://huggingface.co/distilbert/distilroberta-base) para predecir una palabra enmascarada.
+
+### Entrenamiento
+
+
+
+Carga DistilRoBERTa con [`AutoModelForMaskedlM`]:
+
+```py
+>>> from transformers import AutoModelForMaskedLM
+
+>>> model = AutoModelForMaskedLM.from_pretrained("distilbert/distilroberta-base")
+```
+
+
+
+Si no estás familiarizado con el proceso de realizar fine-tuning sobre un modelo con [`Trainer`], considera el tutorial básico [aquí](../training#finetune-with-trainer)!
+
+
+
+A este punto, solo faltan tres pasos:
+
+1. Definir tus hiperparámetros de entrenamiento en [`TrainingArguments`].
+2. Pasarle los argumentos de entrenamiento a [`Trainer`] junto con el modelo, dataset, y el data collator.
+3. Realiza la llamada [`~Trainer.train`] para realizar el fine-tuning de tu modelo.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="./results",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=lm_dataset["train"],
+... eval_dataset=lm_dataset["test"],
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+
+Para realizar el fine-tuning de un modelo en TensorFlow, comienza por convertir tus datasets al formato `tf.data.Dataset` con [`to_tf_dataset`](https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.to_tf_dataset). Especifica los inputs y etiquetas en `columns`, ya sea para mezclar el dataset, tamaño de lote, y el data collator:
+
+```py
+>>> tf_train_set = lm_dataset["train"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "labels"],
+... dummy_labels=True,
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = lm_dataset["test"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "labels"],
+... dummy_labels=True,
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+
+
+Si no estás familiarizado con realizar fine-tuning de tus modelos con Keras, considera el tutorial básico [aquí](training#finetune-with-keras)!
+
+
+
+Crea la función optimizadora, la tasa de aprendizaje, y algunos hiperparámetros de entrenamiento:
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+Carga DistilRoBERTa con [`TFAutoModelForMaskedLM`]:
+
+```py
+>>> from transformers import TFAutoModelForMaskedLM
+
+>>> model = TFAutoModelForCausalLM.from_pretrained("distilbert/distilroberta-base")
+```
+
+Configura el modelo para entrenamiento con [`compile`](https://keras.io/api/models/model_training_apis/#compile-method):
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+Llama a [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) para realizar el fine-tuning del modelo:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3)
+```
+
+
+
+
+
+Para un ejemplo más profundo sobre cómo realizar el fine-tuning sobre un modelo de lenguaje causal, considera
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)
+o [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb).
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/multiple_choice.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/multiple_choice.md
new file mode 100644
index 0000000000000000000000000000000000000000..32df3401d737dea3a95026df707b55984a566bc6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/multiple_choice.md
@@ -0,0 +1,292 @@
+
+
+# Selección múltiple
+
+La tarea de selección múltiple es parecida a la de responder preguntas, con la excepción de que se dan varias opciones de respuesta junto con el contexto. El modelo se entrena para escoger la respuesta correcta
+entre varias opciones a partir del contexto dado.
+
+Esta guía te mostrará como hacerle fine-tuning a [BERT](https://huggingface.co/google-bert/bert-base-uncased) en la configuración `regular` del dataset [SWAG](https://huggingface.co/datasets/swag), de forma
+que seleccione la mejor respuesta a partir de varias opciones y algún contexto.
+
+## Cargar el dataset SWAG
+
+Carga el dataset SWAG con la biblioteca 🤗 Datasets:
+
+```py
+>>> from datasets import load_dataset
+
+>>> swag = load_dataset("swag", "regular")
+```
+
+Ahora, échale un vistazo a un ejemplo del dataset:
+
+```py
+>>> swag["train"][0]
+{'ending0': 'passes by walking down the street playing their instruments.',
+ 'ending1': 'has heard approaching them.',
+ 'ending2': "arrives and they're outside dancing and asleep.",
+ 'ending3': 'turns the lead singer watches the performance.',
+ 'fold-ind': '3416',
+ 'gold-source': 'gold',
+ 'label': 0,
+ 'sent1': 'Members of the procession walk down the street holding small horn brass instruments.',
+ 'sent2': 'A drum line',
+ 'startphrase': 'Members of the procession walk down the street holding small horn brass instruments. A drum line',
+ 'video-id': 'anetv_jkn6uvmqwh4'}
+```
+
+Los campos `sent1` y `sent2` muestran cómo comienza una oración, y cada campo `ending` indica cómo podría terminar. Dado el comienzo de la oración, el modelo debe escoger el final de oración correcto indicado por el campo `label`.
+
+## Preprocesmaiento
+
+Carga el tokenizer de BERT para procesar el comienzo de cada oración y los cuatro finales posibles:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+```
+
+La función de preprocesmaiento debe hacer lo siguiente:
+
+1. Hacer cuatro copias del campo `sent1` de forma que se pueda combinar cada una con el campo `sent2` para recrear la forma en que empieza la oración.
+2. Combinar `sent2` con cada uno de los cuatro finales de oración posibles.
+3. Aplanar las dos listas para que puedas tokenizarlas, y luego des-aplanarlas para que cada ejemplo tenga los campos `input_ids`, `attention_mask` y `labels` correspondientes.
+
+```py
+>>> ending_names = ["ending0", "ending1", "ending2", "ending3"]
+
+
+>>> def preprocess_function(examples):
+... first_sentences = [[context] * 4 for context in examples["sent1"]]
+... question_headers = examples["sent2"]
+... second_sentences = [
+... [f"{header} {examples[end][i]}" for end in ending_names] for i, header in enumerate(question_headers)
+... ]
+
+... first_sentences = sum(first_sentences, [])
+... second_sentences = sum(second_sentences, [])
+
+... tokenized_examples = tokenizer(first_sentences, second_sentences, truncation=True)
+... return {k: [v[i : i + 4] for i in range(0, len(v), 4)] for k, v in tokenized_examples.items()}
+```
+
+Usa la función [`~datasets.Dataset.map`] de 🤗 Datasets para aplicarle la función de preprocesamiento al dataset entero. Puedes acelerar la función `map` haciendo `batched=True` para procesar varios elementos del dataset a la vez.
+
+```py
+tokenized_swag = swag.map(preprocess_function, batched=True)
+```
+
+🤗 Transformers no tiene un collator de datos para la tarea de selección múltiple, así que tendrías que crear uno. Puedes adaptar el [`DataCollatorWithPadding`] para crear un lote de ejemplos para selección múltiple. Este también
+le *añadirá relleno de manera dinámica* a tu texto y a las etiquetas para que tengan la longitud del elemento más largo en su lote, de forma que tengan una longitud uniforme. Aunque es posible rellenar el texto en la función `tokenizer` haciendo
+`padding=True`, el rellenado dinámico es más eficiente.
+
+El `DataCollatorForMultipleChoice` aplanará todas las entradas del modelo, les aplicará relleno y luego des-aplanará los resultados:
+
+
+
+```py
+>>> from dataclasses import dataclass
+>>> from transformers.tokenization_utils_base import PreTrainedTokenizerBase, PaddingStrategy
+>>> from typing import Optional, Union
+>>> import torch
+
+
+>>> @dataclass
+... class DataCollatorForMultipleChoice:
+... """
+... Collator de datos que le añadirá relleno de forma automática a las entradas recibidas para
+... una tarea de selección múltiple.
+... """
+
+... tokenizer: PreTrainedTokenizerBase
+... padding: Union[bool, str, PaddingStrategy] = True
+... max_length: Optional[int] = None
+... pad_to_multiple_of: Optional[int] = None
+
+... def __call__(self, features):
+... label_name = "label" if "label" in features[0].keys() else "labels"
+... labels = [feature.pop(label_name) for feature in features]
+... batch_size = len(features)
+... num_choices = len(features[0]["input_ids"])
+... flattened_features = [
+... [{k: v[i] for k, v in feature.items()} for i in range(num_choices)] for feature in features
+... ]
+... flattened_features = sum(flattened_features, [])
+
+... batch = self.tokenizer.pad(
+... flattened_features,
+... padding=self.padding,
+... max_length=self.max_length,
+... pad_to_multiple_of=self.pad_to_multiple_of,
+... return_tensors="pt",
+... )
+
+... batch = {k: v.view(batch_size, num_choices, -1) for k, v in batch.items()}
+... batch["labels"] = torch.tensor(labels, dtype=torch.int64)
+... return batch
+```
+
+
+```py
+>>> from dataclasses import dataclass
+>>> from transformers.tokenization_utils_base import PreTrainedTokenizerBase, PaddingStrategy
+>>> from typing import Optional, Union
+>>> import tensorflow as tf
+
+
+>>> @dataclass
+... class DataCollatorForMultipleChoice:
+... """
+... Data collator that will dynamically pad the inputs for multiple choice received.
+... """
+
+... tokenizer: PreTrainedTokenizerBase
+... padding: Union[bool, str, PaddingStrategy] = True
+... max_length: Optional[int] = None
+... pad_to_multiple_of: Optional[int] = None
+
+... def __call__(self, features):
+... label_name = "label" if "label" in features[0].keys() else "labels"
+... labels = [feature.pop(label_name) for feature in features]
+... batch_size = len(features)
+... num_choices = len(features[0]["input_ids"])
+... flattened_features = [
+... [{k: v[i] for k, v in feature.items()} for i in range(num_choices)] for feature in features
+... ]
+... flattened_features = sum(flattened_features, [])
+
+... batch = self.tokenizer.pad(
+... flattened_features,
+... padding=self.padding,
+... max_length=self.max_length,
+... pad_to_multiple_of=self.pad_to_multiple_of,
+... return_tensors="tf",
+... )
+
+... batch = {k: tf.reshape(v, (batch_size, num_choices, -1)) for k, v in batch.items()}
+... batch["labels"] = tf.convert_to_tensor(labels, dtype=tf.int64)
+... return batch
+```
+
+
+
+## Entrenamiento
+
+
+
+Carga el modelo BERT con [`AutoModelForMultipleChoice`]:
+
+```py
+>>> from transformers import AutoModelForMultipleChoice, TrainingArguments, Trainer
+
+>>> model = AutoModelForMultipleChoice.from_pretrained("google-bert/bert-base-uncased")
+```
+
+
+
+Para familiarizarte con el fine-tuning con [`Trainer`], ¡mira el tutorial básico [aquí](../training#finetune-with-trainer)!
+
+
+
+En este punto, solo quedan tres pasos:
+
+1. Definir tus hiperparámetros de entrenamiento en [`TrainingArguments`].
+2. Pasarle los argumentos del entrenamiento al [`Trainer`] jnto con el modelo, el dataset, el tokenizer y el collator de datos.
+3. Invocar el método [`~Trainer.train`] para realizar el fine-tuning del modelo.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="./results",
+... eval_strategy="epoch",
+... learning_rate=5e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_swag["train"],
+... eval_dataset=tokenized_swag["validation"],
+... processing_class=tokenizer,
+... data_collator=DataCollatorForMultipleChoice(tokenizer=tokenizer),
+... )
+
+>>> trainer.train()
+```
+
+
+Para realizar el fine-tuning de un modelo en TensorFlow, primero convierte tus datasets al formato `tf.data.Dataset` con el método [`~TFPreTrainedModel.prepare_tf_dataset`].
+
+```py
+>>> data_collator = DataCollatorForMultipleChoice(tokenizer=tokenizer)
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_swag["train"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_swag["validation"],
+... shuffle=False,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+```
+
+
+
+Para familiarizarte con el fine-tuning con Keras, ¡mira el tutorial básico [aquí](training#finetune-with-keras)!
+
+
+
+Prepara una función de optimización, un programa para la tasa de aprendizaje y algunos hiperparámetros de entrenamiento:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_train_epochs = 2
+>>> total_train_steps = (len(tokenized_swag["train"]) // batch_size) * num_train_epochs
+>>> optimizer, schedule = create_optimizer(init_lr=5e-5, num_warmup_steps=0, num_train_steps=total_train_steps)
+```
+
+Carga el modelo BERT con [`TFAutoModelForMultipleChoice`]:
+
+```py
+>>> from transformers import TFAutoModelForMultipleChoice
+
+>>> model = TFAutoModelForMultipleChoice.from_pretrained("google-bert/bert-base-uncased")
+```
+
+Configura el modelo para entrenarlo con [`compile`](https://keras.io/api/models/model_training_apis/#compile-method):
+
+```py
+>>> model.compile(optimizer=optimizer)
+```
+
+Invoca el método [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) para realizar el fine-tuning del modelo:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=2)
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/question_answering.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/question_answering.md
new file mode 100644
index 0000000000000000000000000000000000000000..42a6e4b6e1bc4ee3af2d6e760054b398db9b5d48
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/question_answering.md
@@ -0,0 +1,275 @@
+
+
+# Respuesta a preguntas
+
+
+
+Revisa la [página de la tarea](https://huggingface.co/tasks/question-answering) de responder preguntas para tener más información sobre otras formas de responder preguntas y los modelos, datasets y métricas asociadas.
+
+
+
+## Carga el dataset SQuAD
+
+Carga el dataset SQuAD con la biblioteca 🤗 Datasets:
+
+```py
+>>> from datasets import load_dataset
+
+>>> squad = load_dataset("squad")
+```
+
+Ahora, échale un vistazo a una muestra:
+
+```py
+>>> squad["train"][0]
+{'answers': {'answer_start': [515], 'text': ['Saint Bernadette Soubirous']},
+ 'context': 'Architecturally, the school has a Catholic character. Atop the Main Building\'s gold dome is a golden statue of the Virgin Mary. Immediately in front of the Main Building and facing it, is a copper statue of Christ with arms upraised with the legend "Venite Ad Me Omnes". Next to the Main Building is the Basilica of the Sacred Heart. Immediately behind the basilica is the Grotto, a Marian place of prayer and reflection. It is a replica of the grotto at Lourdes, France where the Virgin Mary reputedly appeared to Saint Bernadette Soubirous in 1858. At the end of the main drive (and in a direct line that connects through 3 statues and the Gold Dome), is a simple, modern stone statue of Mary.',
+ 'id': '5733be284776f41900661182',
+ 'question': 'To whom did the Virgin Mary allegedly appear in 1858 in Lourdes France?',
+ 'title': 'University_of_Notre_Dame'
+}
+```
+
+El campo `answers` es un diccionario que contiene la posición inicial de la respuesta y el `texto` de la respuesta.
+
+## Preprocesamiento
+
+
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+```
+
+
+
+## Entrenamiento
+
+
+
+Carga el modelo DistilBERT con [`AutoModelForQuestionAnswering`]:
+
+```py
+>>> from transformers import AutoModelForQuestionAnswering, TrainingArguments, Trainer
+
+>>> model = AutoModelForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+Para familiarizarte con el fine-tuning con [`Trainer`], ¡mira el tutorial básico [aquí](../training#finetune-with-trainer)!
+
+
+
+En este punto, solo quedan tres pasos:
+
+1. Definir tus hiperparámetros de entrenamiento en [`TrainingArguments`].
+2. Pasarle los argumentos del entrenamiento al [`Trainer`] junto con el modelo, el dataset, el tokenizer y el collator de datos.
+3. Invocar el método [`~Trainer.train`] para realizar el fine-tuning del modelo.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="./results",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_squad["train"],
+... eval_dataset=tokenized_squad["validation"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+
+Para realizar el fine-tuning de un modelo en TensorFlow, primero convierte tus datasets al formato `tf.data.Dataset` con el método [`~TFPreTrainedModel.prepare_tf_dataset`].
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_squad["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_squad["validation"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+
+
+Para familiarizarte con el fine-tuning con Keras, ¡mira el tutorial básico [aquí](training#finetune-with-keras)!
+
+
+
+Prepara una función de optimización, un programa para la tasa de aprendizaje y algunos hiperparámetros de entrenamiento:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_epochs = 2
+>>> total_train_steps = (len(tokenized_squad["train"]) // batch_size) * num_epochs
+>>> optimizer, schedule = create_optimizer(
+... init_lr=2e-5,
+... num_warmup_steps=0,
+... num_train_steps=total_train_steps,
+... )
+```
+
+Carga el modelo DistilBERT con [`TFAutoModelForQuestionAnswering`]:
+
+```py
+>>> from transformers import TFAutoModelForQuestionAnswering
+
+>>> model = TFAutoModelForQuestionAnswering("distilbert/distilbert-base-uncased")
+```
+
+Configura el modelo para entrenarlo con [`compile`](https://keras.io/api/models/model_training_apis/#compile-method):
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+Invoca el método [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) para realizar el fine-tuning del modelo:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3)
+```
+
+
+
+
+
+Para un ejemplo con mayor profundidad de cómo hacer fine-tuning a un modelo para responder preguntas, échale un vistazo al
+[cuaderno de PyTorch](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb) o al
+[cuaderno de TensorFlow](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering-tf.ipynb) correspondiente.
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/summarization.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/summarization.md
new file mode 100644
index 0000000000000000000000000000000000000000..c9060cba6b771db41ee71be6e29af77345f14fc9
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks/summarization.md
@@ -0,0 +1,226 @@
+
+
+# Generación de resúmenes
+
+
+
+Consulta la [página de la tarea](https://huggingface.co/tasks/summarization) de generación de resúmenes para obtener más información sobre sus modelos, datasets y métricas asociadas.
+
+
+
+## Carga el dataset BillSum
+
+Carga el dataset BillSum de la biblioteca 🤗 Datasets:
+
+```py
+>>> from datasets import load_dataset
+
+>>> billsum = load_dataset("billsum", split="ca_test")
+```
+
+Divide el dataset en un set de train y un set de test:
+
+```py
+>>> billsum = billsum.train_test_split(test_size=0.2)
+```
+
+A continuación, observa un ejemplo:
+
+```py
+>>> billsum["train"][0]
+{'summary': 'Existing law authorizes state agencies to enter into contracts for the acquisition of goods or services upon approval by the Department of General Services. Existing law sets forth various requirements and prohibitions for those contracts, including, but not limited to, a prohibition on entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between spouses and domestic partners or same-sex and different-sex couples in the provision of benefits. Existing law provides that a contract entered into in violation of those requirements and prohibitions is void and authorizes the state or any person acting on behalf of the state to bring a civil action seeking a determination that a contract is in violation and therefore void. Under existing law, a willful violation of those requirements and prohibitions is a misdemeanor.\nThis bill would also prohibit a state agency from entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between employees on the basis of gender identity in the provision of benefits, as specified. By expanding the scope of a crime, this bill would impose a state-mandated local program.\nThe California Constitution requires the state to reimburse local agencies and school districts for certain costs mandated by the state. Statutory provisions establish procedures for making that reimbursement.\nThis bill would provide that no reimbursement is required by this act for a specified reason.',
+ 'text': 'The people of the State of California do enact as follows:\n\n\nSECTION 1.\nSection 10295.35 is added to the Public Contract Code, to read:\n10295.35.\n(a) (1) Notwithstanding any other law, a state agency shall not enter into any contract for the acquisition of goods or services in the amount of one hundred thousand dollars ($100,000) or more with a contractor that, in the provision of benefits, discriminates between employees on the basis of an employee’s or dependent’s actual or perceived gender identity, including, but not limited to, the employee’s or dependent’s identification as transgender.\n(2) For purposes of this section, “contract” includes contracts with a cumulative amount of one hundred thousand dollars ($100,000) or more per contractor in each fiscal year.\n(3) For purposes of this section, an employee health plan is discriminatory if the plan is not consistent with Section 1365.5 of the Health and Safety Code and Section 10140 of the Insurance Code.\n(4) The requirements of this section shall apply only to those portions of a contractor’s operations that occur under any of the following conditions:\n(A) Within the state.\n(B) On real property outside the state if the property is owned by the state or if the state has a right to occupy the property, and if the contractor’s presence at that location is connected to a contract with the state.\n(C) Elsewhere in the United States where work related to a state contract is being performed.\n(b) Contractors shall treat as confidential, to the maximum extent allowed by law or by the requirement of the contractor’s insurance provider, any request by an employee or applicant for employment benefits or any documentation of eligibility for benefits submitted by an employee or applicant for employment.\n(c) After taking all reasonable measures to find a contractor that complies with this section, as determined by the state agency, the requirements of this section may be waived under any of the following circumstances:\n(1) There is only one prospective contractor willing to enter into a specific contract with the state agency.\n(2) The contract is necessary to respond to an emergency, as determined by the state agency, that endangers the public health, welfare, or safety, or the contract is necessary for the provision of essential services, and no entity that complies with the requirements of this section capable of responding to the emergency is immediately available.\n(3) The requirements of this section violate, or are inconsistent with, the terms or conditions of a grant, subvention, or agreement, if the agency has made a good faith attempt to change the terms or conditions of any grant, subvention, or agreement to authorize application of this section.\n(4) The contractor is providing wholesale or bulk water, power, or natural gas, the conveyance or transmission of the same, or ancillary services, as required for ensuring reliable services in accordance with good utility practice, if the purchase of the same cannot practically be accomplished through the standard competitive bidding procedures and the contractor is not providing direct retail services to end users.\n(d) (1) A contractor shall not be deemed to discriminate in the provision of benefits if the contractor, in providing the benefits, pays the actual costs incurred in obtaining the benefit.\n(2) If a contractor is unable to provide a certain benefit, despite taking reasonable measures to do so, the contractor shall not be deemed to discriminate in the provision of benefits.\n(e) (1) Every contract subject to this chapter shall contain a statement by which the contractor certifies that the contractor is in compliance with this section.\n(2) The department or other contracting agency shall enforce this section pursuant to its existing enforcement powers.\n(3) (A) If a contractor falsely certifies that it is in compliance with this section, the contract with that contractor shall be subject to Article 9 (commencing with Section 10420), unless, within a time period specified by the department or other contracting agency, the contractor provides to the department or agency proof that it has complied, or is in the process of complying, with this section.\n(B) The application of the remedies or penalties contained in Article 9 (commencing with Section 10420) to a contract subject to this chapter shall not preclude the application of any existing remedies otherwise available to the department or other contracting agency under its existing enforcement powers.\n(f) Nothing in this section is intended to regulate the contracting practices of any local jurisdiction.\n(g) This section shall be construed so as not to conflict with applicable federal laws, rules, or regulations. In the event that a court or agency of competent jurisdiction holds that federal law, rule, or regulation invalidates any clause, sentence, paragraph, or section of this code or the application thereof to any person or circumstances, it is the intent of the state that the court or agency sever that clause, sentence, paragraph, or section so that the remainder of this section shall remain in effect.\nSEC. 2.\nSection 10295.35 of the Public Contract Code shall not be construed to create any new enforcement authority or responsibility in the Department of General Services or any other contracting agency.\nSEC. 3.\nNo reimbursement is required by this act pursuant to Section 6 of Article XIII\u2009B of the California Constitution because the only costs that may be incurred by a local agency or school district will be incurred because this act creates a new crime or infraction, eliminates a crime or infraction, or changes the penalty for a crime or infraction, within the meaning of Section 17556 of the Government Code, or changes the definition of a crime within the meaning of Section 6 of Article XIII\u2009B of the California Constitution.',
+ 'title': 'An act to add Section 10295.35 to the Public Contract Code, relating to public contracts.'}
+```
+
+El campo `text` es el input y el campo `summary` es el objetivo.
+
+## Preprocesa
+
+Carga el tokenizador T5 para procesar `text` y `summary`:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+```
+
+La función de preprocesamiento necesita:
+
+1. Agregar un prefijo al input; una clave para que T5 sepa que se trata de una tarea de generación de resúmenes. Algunos modelos capaces de realizar múltiples tareas de NLP requieren una clave que indique la tarea específica.
+2. Usar el argumento `text_target` para tokenizar etiquetas.
+3. Truncar secuencias para que no sean más largas que la longitud máxima fijada por el parámetro `max_length`.
+
+```py
+>>> prefix = "summarize: "
+
+
+>>> def preprocess_function(examples):
+... inputs = [prefix + doc for doc in examples["text"]]
+... model_inputs = tokenizer(inputs, max_length=1024, truncation=True)
+
+... labels = tokenizer(text_target=examples["summary"], max_length=128, truncation=True)
+
+... model_inputs["labels"] = labels["input_ids"]
+... return model_inputs
+```
+
+Usa la función [`~datasets.Dataset.map`] de 🤗 Datasets para aplicar la función de preprocesamiento sobre el dataset en su totalidad. Puedes acelerar la función `map` configurando el argumento `batched=True` para procesar múltiples elementos del dataset a la vez:
+
+```py
+>>> tokenized_billsum = billsum.map(preprocess_function, batched=True)
+```
+
+Usa [`DataCollatorForSeq2Seq`] para crear un lote de ejemplos. Esto también *rellenará dinámicamente* tu texto y etiquetas a la dimensión del elemento más largo del lote para que tengan un largo uniforme. Si bien es posible rellenar tu texto en la función `tokenizer` mediante el argumento `padding=True`, el rellenado dinámico es más eficiente.
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=model)
+```
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=model, return_tensors="tf")
+```
+
+
+
+## Entrenamiento
+
+
+
+Carga T5 con [`AutoModelForSeq2SeqLM`]:
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM, Seq2SeqTrainingArguments, Seq2SeqTrainer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("google-t5/t5-small")
+```
+
+
+
+Para familiarizarte con el proceso para realizar fine-tuning sobre un modelo con [`Trainer`], ¡mira el tutorial básico [aquí](../training#finetune-with-trainer)!
+
+
+
+En este punto, solo faltan tres pasos:
+
+1. Definir tus hiperparámetros de entrenamiento en [`Seq2SeqTrainingArguments`].
+2. Pasarle los argumentos de entrenamiento a [`Seq2SeqTrainer`] junto con el modelo, dataset y data collator.
+3. Llamar [`~Trainer.train`] para realizar el fine-tuning sobre tu modelo.
+
+```py
+>>> training_args = Seq2SeqTrainingArguments(
+... output_dir="./results",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... weight_decay=0.01,
+... save_total_limit=3,
+... num_train_epochs=1,
+... fp16=True,
+... )
+
+>>> trainer = Seq2SeqTrainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_billsum["train"],
+... eval_dataset=tokenized_billsum["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+
+Para hacer fine-tuning de un modelo en TensorFlow, comienza por convertir tus datasets al formato `tf.data.Dataset` con [`~datasets.Dataset.to_tf_dataset`]. Especifica los inputs y etiquetas en `columns`, el tamaño de lote, el data collator, y si es necesario mezclar el dataset:
+
+```py
+>>> tf_train_set = tokenized_billsum["train"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "labels"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = tokenized_billsum["test"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "labels"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+
+
+Para familiarizarte con el fine-tuning con Keras, ¡mira el tutorial básico [aquí](training#finetune-with-keras)!
+
+
+
+Crea la función optimizadora, establece la tasa de aprendizaje y algunos hiperparámetros de entrenamiento:
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+Carga T5 con [`TFAutoModelForSeq2SeqLM`]:
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained("google-t5/t5-small")
+```
+
+Configura el modelo para entrenamiento con [`compile`](https://keras.io/api/models/model_training_apis/#compile-method):
+
+```py
+>>> model.compile(optimizer=optimizer)
+```
+
+Llama a [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) para realizar el fine-tuning del modelo:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3)
+```
+
+
+
+
+
+Para un ejemplo con mayor profundidad de cómo hacer fine-tuning a un modelo para generación de resúmenes, revisa la
+[notebook en PyTorch](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization.ipynb)
+o a la [notebook en TensorFlow](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization-tf.ipynb).
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks_explained.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks_explained.md
new file mode 100644
index 0000000000000000000000000000000000000000..9b13f521417890a329a758e1b8fb68b9b1727507
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tasks_explained.md
@@ -0,0 +1,295 @@
+
+
+# ¿Cómo los 🤗 Transformers resuelven tareas?
+
+En [Lo que 🤗 Transformers puede hacer](task_summary), aprendiste sobre el procesamiento de lenguaje natural (NLP), tareas de voz y audio, visión por computadora y algunas aplicaciones importantes de ellas. Esta página se centrará en cómo los modelos resuelven estas tareas y explicará lo que está sucediendo debajo de la superficie. Hay muchas maneras de resolver una tarea dada, y diferentes modelos pueden implementar ciertas técnicas o incluso abordar la tarea desde un ángulo nuevo, pero para los modelos Transformer, la idea general es la misma. Debido a su arquitectura flexible, la mayoría de los modelos son una variante de una estructura de codificador, descodificador o codificador-descodificador. Además de los modelos Transformer, nuestra biblioteca también tiene varias redes neuronales convolucionales (CNNs) modernas, que todavía se utilizan hoy en día para tareas de visión por computadora. También explicaremos cómo funciona una CNN moderna.
+
+Para explicar cómo se resuelven las tareas, caminaremos a través de lo que sucede dentro del modelo para generar predicciones útiles.
+
+- [Wav2Vec2](https://huggingface.co/docs/transformers/model_doc/wav2vec2) para clasificación de audio y reconocimiento automático de habla (ASR)
+- [Transformador de Visión (ViT)](https://huggingface.co/docs/transformers/model_doc/vit) y [ConvNeXT](https://huggingface.co/docs/transformers/model_doc/convnext) para clasificación de imágenes
+- [DETR](https://huggingface.co/docs/transformers/model_doc/detr) para detección de objetos
+- [Mask2Former](https://huggingface.co/docs/transformers/model_doc/mask2former) para segmentación de imagen
+- [GLPN](https://huggingface.co/docs/transformers/model_doc/glpn) para estimación de profundidad
+- [BERT](https://huggingface.co/docs/transformers/model_doc/bert) para tareas de NLP como clasificación de texto, clasificación de tokens y preguntas y respuestas que utilizan un codificador
+- [GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2) para tareas de NLP como generación de texto que utilizan un descodificador
+- [BART](https://huggingface.co/docs/transformers/model_doc/bart) para tareas de NLP como resumen y traducción que utilizan un codificador-descodificador
+
+
+
+Antes de continuar, es bueno tener un conocimiento básico de la arquitectura original del Transformer. Saber cómo funcionan los codificadores, decodificadores y la atención te ayudará a entender cómo funcionan los diferentes modelos de Transformer. Si estás empezando o necesitas repasar, ¡echa un vistazo a nuestro [curso](https://huggingface.co/course/chapter1/4?fw=pt) para obtener más información!
+
+
+
+## Habla y audio
+
+[Wav2Vec2](https://huggingface.co/docs/transformers/model_doc/wav2vec2) es un modelo auto-supervisado preentrenado en datos de habla no etiquetados y ajustado en datos etiquetados para clasificación de audio y reconocimiento automático de voz.
+
+
+
+
+
+Un tercer enfoque combina Transformers con convoluciones (por ejemplo, [Convolutional Vision Transformer](https://huggingface.co/docs/transformers/model_doc/cvt) o [LeViT](https://huggingface.co/docs/transformers/model_doc/levit)). No discutiremos estos porque simplemente combinan los dos enfoques que examinamos aquí.
+
+
+
+ViT y ConvNeXT se utilizan comúnmente para la clasificación de imágenes, pero para otras tareas de visión como la detección de objetos, la segmentación y la estimación de profundidad, veremos DETR, Mask2Former y GLPN, respectivamente; estos modelos son más adecuados para esas tareas.
+
+### Clasificación de imágenes
+
+ViT y ConvNeXT pueden usarse ambos para la clasificación de imágenes; la diferencia principal es que ViT utiliza un mecanismo de atención mientras que ConvNeXT utiliza convoluciones.
+
+#### Transformer
+
+[ViT](https://huggingface.co/docs/transformers/model_doc/vit) reemplaza completamente las convoluciones con una arquitectura de Transformer pura. Si estás familiarizado con el Transformer original, entonces ya estás en el camino para entender ViT.
+
+
+
+
+
+Esta sección explica brevemente las convoluciones, pero sería útil tener un entendimiento previo de cómo cambian la forma y el tamaño de una imagen. Si no estás familiarizado con las convoluciones, ¡echa un vistazo al [capítulo de Redes Neuronales Convolucionales](https://github.com/fastai/fastbook/blob/master/13_convolutions.ipynb) del libro fastai!
+
+
+
+[ConvNeXT](https://huggingface.co/docs/transformers/model_doc/convnext) es una arquitectura de CNN que adopta diseños de redes nuevas y modernas para mejorar el rendimiento. Sin embargo, las convoluciones siguen siendo el núcleo del modelo. Desde una perspectiva de alto nivel, una [convolución](glossary#convolution) es una operación donde una matriz más pequeña (*kernel*) se multiplica por una pequeña ventana de píxeles de la imagen. Esta calcula algunas características de ella, como una textura particular o la curvatura de una línea. Luego, se desliza hacia la siguiente ventana de píxeles; la distancia que recorre la convolución se conoce como el *stride*.
+
+
+
+
Una convolución básica sin relleno ni paso, tomada de Una guía para la aritmética de convoluciones para el aprendizaje profundo.
+
+Puedes alimentar esta salida a otra capa convolucional, y con cada capa sucesiva, la red aprende cosas más complejas y abstractas como perros calientes o cohetes. Entre capas convolucionales, es común añadir una capa de agrupación para reducir la dimensionalidad y hacer que el modelo sea más robusto a las variaciones de la posición de una característica.
+
+
+
+
+
+
+
+
+
+
+
+💡 ¡Observa lo fácil que es usar BERT para diferentes tareas una vez que ha sido preentrenado! ¡Solo necesitas añadir una cabecera específica al modelo preentrenado para manipular los estados ocultos en tu salida deseada!
+
+
+
+### Generación de texto
+
+[GPT-2](https://huggingface.co/docs/transformers/model_doc/gpt2) es un modelo que solo tiene decodificador y se preentrena en una gran cantidad de texto. Puede generar texto convincente (¡aunque no siempre verdadero!) dado un estímulo y completar otras tareas de procesamiento del lenguaje natural como responder preguntas, a pesar de no haber sido entrenado explícitamente para ello.
+
+
+
+
+
+Para obtener más información sobre la generación de texto, ¡consulta la guía de [estrategias de generación de texto](https://huggingface.co/docs/transformers/generation_strategies)!
+
+
+
+### Resumir
+
+Los modelos codificador-decodificador como [BART](https://huggingface.co/docs/transformers/model_doc/bart) y [T5](https://huggingface.co/docs/transformers/model_doc/t5) están diseñados para el patrón de secuencia a secuencia de una tarea de resumen. Explicaremos cómo funciona BART en esta sección, y luego podrás probar el ajuste fino de T5 al final.
+
+
+
+
+
+Para obtener más información sobre la generación de texto, ¡consulta la guía de [estrategias de generación de texto](https://huggingface.co/docs/transformers/generation_strategies)!
+
+
+
+### Traducción
+
+La traducción es otro ejemplo de una tarea de secuencia a secuencia, lo que significa que puedes usar un modelo codificador-decodificador como [BART](https://huggingface.co/docs/transformers/model_doc/bart) o [T5](https://huggingface.co/docs/transformers/model_doc/t5) para hacerlo. Explicaremos cómo funciona BART en esta sección, y luego podrás probar el ajuste fino de T5 al final.
+
+BART se adapta a la traducción añadiendo un codificador separado inicializado aleatoriamente para mapear un idioma fuente a una entrada que pueda ser decodificada en el idioma objetivo. Las incrustaciones de este nuevo codificador se pasan al codificador preentrenado en lugar de las incrustaciones de palabras originales. El codificador de origen se entrena actualizando el codificador de origen, las incrustaciones posicionales y las incrustaciones de entrada con la pérdida de entropía cruzada de la salida del modelo. Los parámetros del modelo están congelados en este primer paso, y todos los parámetros del modelo se entrenan juntos en el segundo paso.
+
+Desde entonces, BART ha sido seguido por una versión multilingüe, mBART, destinada a la traducción y preentrenada en muchos idiomas diferentes.
+
+¿Listo para probar la traducción? ¡Consulta nuestra guía completa de [traducción](https://huggingface.co/docs/transformers/tasks/translation) para aprender cómo ajustar T5 y usarlo para inferencia!
+
+
+
+Para obtener más información sobre la generación de texto, ¡consulta la guía de [estrategias de generación de texto](https://huggingface.co/docs/transformers/generation_strategies)!
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tokenizer_summary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tokenizer_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..c4c8ee1783b251f917b37b2df7d661b1812fe49f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/tokenizer_summary.md
@@ -0,0 +1,175 @@
+
+
+# Descripción general de los tokenizadores
+
+[[open-in-colab]]
+
+En esta página, veremos más de cerca la tokenización.
+
+", "ug"]` ya que el símbolo `"m"` no está en el vocabulario base. En general, las letras individuales como `"m"` no se reemplazan por el símbolo `""` porque los datos de entrenamiento usualmente incluyen al menos una ocurrencia de cada letra, pero es probable que suceda para caracteres especiales como los emojis.
+
+Como se mencionó anteriormente, el tamaño del vocabulario, es decir, el tamaño del vocabulario base + el número de combinaciones, es un hiperparámetro que se debe elegir. Por ejemplo, [GPT](https://huggingface.co/docs/transformers/en/model_doc/openai-gpt) tiene un tamaño de vocabulario de 40,478 ya que tienen 478 caracteres base y eligieron detener el entrenamiento después de 40,000 combinaciones.
+
+#### Byte-level BPE
+
+Un vocabulario base que incluya todos los caracteres base posibles puede ser bastante extenso si, por ejemplo, se consideran todos los caracteres unicode como caracteres base. Para tener un vocabulario base mejor, [GPT-2](https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf) utiliza bytes como vocabulario base, lo que es un truco astuto para forzar el vocabulario base a ser de tamaño 256 mientras se asegura de que cada carácter base esté incluido en el vocabulario. Con algunas reglas adicionales para tratar con la puntuación, el tokenizador de GPT2 puede tokenizar cualquier texto sin la necesidad del símbolo ``. [GPT-2](https://huggingface.co/docs/transformers/en/model_doc/gpt2) tiene un tamaño de vocabulario de 50,257, lo que corresponde a los 256 tokens base de bytes, un token especial de fin de texto y los símbolos aprendidos con 50,000 combinaciones.
+
+
+Este es el comienzo de nuestros experimentos con TorchScript y todavía estamos explorando sus capacidades con modelos de variables de entrada. Es un tema de interés para nosotros y profundizaremos en nuestro análisis en las próximas versiones, con más ejemplos de código, una implementación más flexible y comparativas de rendimiento comparando códigos basados en Python con TorchScript compilado.
+
+
+
+De acuerdo con la documentación de TorchScript:
+
+> "TorchScript es una manera de crear modelos serializables y optimizables a partir del código PyTorch."
+
+Hay dos módulos de PyTorch, [JIT y TRACE](https://pytorch.org/docs/stable/jit.html), que permiten a los desarrolladores exportar sus modelos para ser reusados en otros programas, como los programas de C++ orientados a la eficiencia.
+
+Nosotros proveemos una interface que te permite exportar los modelos 🤗Transformers a TorchScript para que puedan ser reusados en un entorno diferente al de los programas Python basados en PyTorch. Aquí explicamos como exportar y usar nuestros modelos utilizando TorchScript.
+
+Exportar un modelo requiere de dos cosas:
+
+- La instanciación del modelo con la bandera TorchScript.
+- Un paso hacia adelante con entradas ficticias.
+
+Estas necesidades implican varias cosas de las que los desarrolladores deben tener cuidado, como se detalla a continuación.
+
+## Bandera TorchScript y pesos atados.
+
+La bandera `torchscript` es necesaria porque la mayoría de los modelos de lenguaje de 🤗Transformers tienen pesos atados entre su `capa de incrustación` (`Embedding`) y su `capa de decodificación` (`Decoding`). TorchScript no te permite exportar modelos que tienen pesos atados, por lo que es necesario desatar y clonar los pesos de antemano.
+
+Los modelos instanciados con la bandera `torchscript` tienen su `capa de incrustación` (`Embedding`) y su `capa de decodificación` (`Decoding`) separadas, lo que significa que no deben ser entrenados más adelante. Entrenar desincronizaría las dos capas, lo que llevaría a resultados inesperados.
+
+Esto no es así para los modelos que no tienen una cabeza de modelo de lenguaje, ya que esos modelos no tienen pesos atados. Estos modelos pueden ser exportados de manera segura sin la bandera `torchscript`.
+
+## Entradas ficticias y longitudes estándar
+
+Las entradas ficticias se utilizan para un paso del modelo hacia adelante. Mientras los valores de las entradas se propagan a través de las capas, PyTorch realiza un seguimiento de las diferentes operaciones ejecutadas en cada tensor. Estas operaciones registradas se utilizan luego para crear *la traza* del modelo.
+La traza se crea en relación con las dimensiones de las entradas. Por lo tanto, está limitada por las dimensiones de la entrada ficticia y no funcionará para ninguna otra longitud de secuencia o tamaño de lote. Cuando se intenta con un tamaño diferente, se genera el siguiente error:
+
+```
+`El tamaño expandido del tensor (3) debe coincidir con el tamaño existente (7) en la dimensión no singleton 2`.
+```
+
+Recomendamos trazar el modelo con un tamaño de entrada ficticio al menos tan grande como la entrada más grande con la que se alimentará al modelo durante la inferencia. El relleno puede ayudar a completar los valores faltantes. Sin embargo, dado que el modelo se traza con un tamaño de entrada más grande, las dimensiones de la matriz también serán grandes, lo que resultará en más cálculos.
+
+Ten cuidado con el número total de operaciones realizadas en cada entrada y sigue de cerca el rendimiento al exportar modelos con longitudes de secuencia variables.
+
+## Usando TorchScript en Python
+
+Esta sección demuestra cómo guardar y cargar modelos, así como cómo usar la traza para la inferencia.
+
+### Guardando un modelo
+
+Para exportar un `BertModel` con TorchScript, instancia `BertModel` a partir de la clase `BertConfig` y luego guárdalo en disco bajo el nombre de archivo `traced_bert.pt`:
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+
+enc = BertTokenizer.from_pretrained("bert-base-uncased")
+
+# Tokenizing input text
+text = "[CLS] Who was Jim Henson ? [SEP] Jim Henson was a puppeteer [SEP]"
+tokenized_text = enc.tokenize(text)
+
+# Masking one of the input tokens
+masked_index = 8
+tokenized_text[masked_index] = "[MASK]"
+indexed_tokens = enc.convert_tokens_to_ids(tokenized_text)
+segments_ids = [0, 0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1]
+
+# Creating a dummy input
+tokens_tensor = torch.tensor([indexed_tokens])
+segments_tensors = torch.tensor([segments_ids])
+dummy_input = [tokens_tensor, segments_tensors]
+
+# Initializing the model with the torchscript flag
+# Flag set to True even though it is not necessary as this model does not have an LM Head.
+config = BertConfig(
+ vocab_size_or_config_json_file=32000,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ torchscript=True,
+)
+
+# Instantiating the model
+model = BertModel(config)
+
+# The model needs to be in evaluation mode
+model.eval()
+
+# If you are instantiating the model with *from_pretrained* you can also easily set the TorchScript flag
+model = BertModel.from_pretrained("bert-base-uncased", torchscript=True)
+
+# Creating the trace
+traced_model = torch.jit.trace(model, [tokens_tensor, segments_tensors])
+torch.jit.save(traced_model, "traced_bert.pt")
+```
+### Cargando un modelo
+
+Ahora puedes cargar el `BertModel` guardado anteriormente, `traced_bert.pt`, desde el disco y usarlo en la entrada ficticia (`dummy_input`) previamente inicializada:
+
+```python
+loaded_model = torch.jit.load("traced_bert.pt")
+loaded_model.eval()
+
+all_encoder_layers, pooled_output = loaded_model(*dummy_input)
+```
+
+## Usando un modelo trazado para inferencia
+
+Utiliza el modelo trazado para inferencia utilizando su método `_call_` dunder:
+
+```python
+traced_model(tokens_tensor, segments_tensors)
+```
+## Despliega modelos TorchScript de Hugging Face en AWS con el Neuron SDK
+
+AWS introdujo la familia de instancias [Amazon EC2 Inf1](https://aws.amazon.com/ec2/instance-types/inf1/) para inferencia de aprendizaje automático de alto rendimiento y bajo costo en la nube. Las instancias Inf1 están alimentadas por el chip AWS Inferentia, un acelerador de hardware personalizado que se especializa en cargas de trabajo de inferencia de aprendizaje profundo. [AWS Neuron](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/#) es el SDK para Inferentia que admite el trazado y la optimización de modelos de transformers para implementación en Inf1. El SDK Neuron proporciona:
+
+1. Una API fácil de usar con un solo cambio de línea de código para trazar y optimizar un modelo TorchScript para inferencia en la nube.
+
+2. Optimizaciones de rendimiento listas para usar [para mejorar el rendimiento y el costo](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/benchmark/>).
+
+3. Soporte para modelos de transformers de Hugging Face construidos tanto con [PyTorch](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/bert_tutorial/tutorial_pretrained_bert.html) como con [TensorFlow](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/tensorflow/huggingface_bert/huggingface_bert.html).
+
+### Implicaciones
+
+Los modelos transformers basados en la arquitectura [BERT (Bidirectional Encoder Representations from Transformers)](https://huggingface.co/docs/transformers/main/model_doc/bert), o sus variantes como [distilBERT](https://huggingface.co/docs/transformers/main/model_doc/distilbert) y [roBERTa](https://huggingface.co/docs/transformers/main/model_doc/roberta), funcionan mejor en Inf1 para tareas no generativas como la respuesta a preguntas extractivas, la clasificación de secuencias y la clasificación de tokens. Sin embargo, las tareas de generación de texto aún pueden adaptarse para ejecutarse en Inf1 según este [tutorial de AWS Neuron MarianMT](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/transformers-marianmt.html). Se puede encontrar más información sobre los modelos que se pueden convertir fácilmente para usar en Inferentia en la sección de [Model Architecture Fit](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/models/models-inferentia.html#models-inferentia) de la documentación de Neuron.
+
+### Dependencias
+
+El uso de AWS Neuron para convertir modelos requiere un [entorno de Neuron SDK](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/neuron-frameworks/pytorch-neuron/index.html#installation-guide) que viene preconfigurado en [la AMI de AWS Deep Learning](https://docs.aws.amazon.com/dlami/latest/devguide/tutorial-inferentia-launching.html).
+
+### Convertir un modelo para AWS Neuron
+
+Convierte un modelo para AWS NEURON utilizando el mismo código de [Uso de TorchScript en Python](torchscript#using-torchscript-in-python) para trazar un `BertModel`. Importa la extensión del framework `torch.neuron` para acceder a los componentes del Neuron SDK a través de una API de Python:
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+import torch.neuron
+```
+Solo necesitas la linea sigueda:
+
+```diff
+- torch.jit.trace(model, [tokens_tensor, segments_tensors])
++ torch.neuron.trace(model, [token_tensor, segments_tensors])
+```
+
+Esto permite que el Neuron SDK trace el modelo y lo optimice para las instancias Inf1.
+
+Para obtener más información sobre las características, herramientas, tutoriales de ejemplo y últimas actualizaciones del AWS Neuron SDK, consulta [la documentación de AWS NeuronSDK](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/index.html).
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/trainer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/trainer.md
new file mode 100644
index 0000000000000000000000000000000000000000..dab83e9a9d9ebcb5b55b33a7cc79952a4403bbe5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/trainer.md
@@ -0,0 +1,409 @@
+
+
+# El Trainer
+
+El [`Trainer`] es un bucle completo de entrenamiento y evaluación para modelos de PyTorch implementado en la biblioteca Transformers. Solo necesitas pasarle las piezas necesarias para el entrenamiento (modelo, tokenizador, conjunto de datos, función de evaluación, hiperparámetros de entrenamiento, etc.), y la clase [`Trainer`] se encarga del resto. Esto facilita comenzar a entrenar más rápido sin tener que escribir manualmente tu propio bucle de entrenamiento. Pero al mismo tiempo, [`Trainer`] es muy personalizable y ofrece una gran cantidad de opciones de entrenamiento para que puedas adaptarlo a tus necesidades exactas de entrenamiento.
+
+
+
+Además de la clase [`Trainer`], Transformers también proporciona una clase [`Seq2SeqTrainer`] para tareas de secuencia a secuencia como traducción o resumen. También está la clase [~trl.SFTTrainer] de la biblioteca [TRL](https://hf.co/docs/trl) que envuelve la clase [`Trainer`] y está optimizada para entrenar modelos de lenguaje como Llama-2 y Mistral con técnicas autoregresivas. [`~trl.SFTTrainer`] también admite funciones como el empaquetado de secuencias, LoRA, cuantización y DeepSpeed para escalar eficientemente a cualquier tamaño de modelo.
+
+
+
+Antes de comenzar, asegúrate de tener instalado [Accelerate](https://hf.co/docs/accelerate), una biblioteca para habilitar y ejecutar el entrenamiento de PyTorch en entornos distribuidos.
+
+```bash
+pip install accelerate
+
+# upgrade
+pip install accelerate --upgrade
+```
+Esta guía proporciona una visión general de la clase [`Trainer`].
+
+## Uso básico
+
+[`Trainer`] incluye todo el código que encontrarías en un bucle de entrenamiento básico:
+1. Realiza un paso de entrenamiento para calcular la pérdida
+2. Calcula los gradientes con el método [~accelerate.Accelerator.backward]
+3. Actualiza los pesos basados en los gradientes
+4. Repite este proceso hasta alcanzar un número predeterminado de épocas
+
+La clase [`Trainer`] abstrae todo este código para que no tengas que preocuparte por escribir manualmente un bucle de entrenamiento cada vez o si estás empezando con PyTorch y el entrenamiento. Solo necesitas proporcionar los componentes esenciales requeridos para el entrenamiento, como un modelo y un conjunto de datos, y la clase [`Trainer`] maneja todo lo demás.
+
+Si deseas especificar opciones de entrenamiento o hiperparámetros, puedes encontrarlos en la clase [`TrainingArguments`]. Por ejemplo, vamos a definir dónde guardar el modelo en output_dir y subir el modelo al Hub después del entrenamiento con `push_to_hub=True`.
+
+```py
+from transformers import TrainingArguments
+
+training_args = TrainingArguments(
+ output_dir="your-model",
+ learning_rate=2e-5,
+ per_device_train_batch_size=16,
+ per_device_eval_batch_size=16,
+ num_train_epochs=2,
+ weight_decay=0.01,
+ eval_strategy="epoch",
+ save_strategy="epoch",
+ load_best_model_at_end=True,
+ push_to_hub=True,
+)
+```
+
+Pase `training_args` al [`Trainer`] con un modelo, un conjunto de datos o algo para preprocesar el conjunto de datos (dependiendo en el tipo de datos pueda ser un tokenizer, extractor de caracteristicas o procesor del imagen), un recopilador de datos y una función para calcular las métricas que desea rastrear durante el entrenamiento.
+
+Finalmente, llame [`~Trainer.train`] para empezar entrenamiento!
+
+```py
+from transformers import Trainer
+
+trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=dataset["train"],
+ eval_dataset=dataset["test"],
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics,
+)
+
+trainer.train()
+```
+
+### Los puntos de control
+
+La clase [`Trainer`] guarda los puntos de control del modelo en el directorio especificado en el parámetro `output_dir` de [`TrainingArguments`]. Encontrarás los puntos de control guardados en una subcarpeta checkpoint-000 donde los números al final corresponden al paso de entrenamiento. Guardar puntos de control es útil para reanudar el entrenamiento más tarde.
+
+```py
+# resume from latest checkpoint
+trainer.train(resume_from_checkpoint=True)
+
+# resume from specific checkpoint saved in output directory
+trainer.train(resume_from_checkpoint="your-model/checkpoint-1000")
+```
+
+Puedes guardar tus puntos de control (por defecto, el estado del optimizador no se guarda) en el Hub configurando `push_to_hub=True` en [`TrainingArguments`] para confirmar y enviarlos. Otras opciones para decidir cómo se guardan tus puntos de control están configuradas en el parámetro [`hub_strategy`](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.hub_strategy):
+
+* hub_strategy="checkpoint" envía el último punto de control a una subcarpeta llamada "last-checkpoint" desde la cual puedes reanudar el entrenamiento.
+
+* hub_strategy="all_checkpoints" envía todos los puntos de control al directorio definido en `output_dir` (verás un punto de control por carpeta en tu repositorio de modelos).
+
+Cuando reanudas el entrenamiento desde un punto de control, el [`Trainer`] intenta mantener los estados de los generadores de números aleatorios (RNG) de Python, NumPy y PyTorch iguales a como estaban cuando se guardó el punto de control. Pero debido a que PyTorch tiene varias configuraciones predeterminadas no determinísticas, no se garantiza que los estados de RNG sean los mismos. Si deseas habilitar la plena determinismo, echa un vistazo a la guía ["Controlling sources of randomness"](https://pytorch.org/docs/stable/notes/randomness#controlling-sources-of-randomness) para aprender qué puedes habilitar para hacer que tu entrenamiento sea completamente determinista. Sin embargo, ten en cuenta que al hacer ciertas configuraciones deterministas, el entrenamiento puede ser más lento.
+
+## Personaliza el Trainer
+
+Si bien la clase [`Trainer`] está diseñada para ser accesible y fácil de usar, también ofrece mucha capacidad de personalización para usuarios más aventureros. Muchos de los métodos del [`Trainer`] pueden ser subclasificados y sobrescritos para admitir la funcionalidad que deseas, sin tener que reescribir todo el bucle de entrenamiento desde cero para adaptarlo. Estos métodos incluyen:
+
+* [~Trainer.get_train_dataloader] crea un entrenamiento de DataLoader
+* [~Trainer.get_eval_dataloader] crea una evaluación DataLoader
+* [~Trainer.get_test_dataloader] crea una prueba de DataLoader
+* [~Trainer.log] anota la información de los objetos varios que observa el entrenamiento
+* [~Trainer.create_optimizer_and_scheduler] crea un optimizador y la tasa programada de aprendizaje si no lo pasaron en __init__; estos pueden ser personalizados independientes con [~Trainer.create_optimizer] y [~Trainer.create_scheduler] respectivamente
+* [~Trainer.compute_loss] computa la pérdida en lote con las aportes del entrenamiento
+* [~Trainer.training_step] realiza el paso del entrenamiento
+* [~Trainer.prediction_step] realiza la predicción y paso de prueba
+* [~Trainer.evaluate] evalua el modelo y da las metricas evaluativas
+* [~Trainer.predict] hace las predicciones (con las metricas si hay etiquetas disponibles) en lote de prueba
+
+Por ejemplo, si deseas personalizar el método [`~Trainer.compute_loss`] para usar una pérdida ponderada en su lugar, puedes hacerlo de la siguiente manera:
+
+```py
+from torch import nn
+from transformers import Trainer
+
+class CustomTrainer(Trainer):
+ def compute_loss(self, model, inputs, return_outputs=False):
+ labels = inputs.pop("labels")
+ # forward pass
+ outputs = model(**inputs)
+ logits = outputs.get("logits")
+ # compute custom loss for 3 labels with different weights
+ loss_fct = nn.CrossEntropyLoss(weight=torch.tensor([1.0, 2.0, 3.0], device=model.device))
+ loss = loss_fct(logits.view(-1, self.model.config.num_labels), labels.view(-1))
+ return (loss, outputs) if return_outputs else loss
+```
+### Callbacks
+
+Otra opción para personalizar el [`Trainer`] es utilizar [callbacks](callbacks). Los callbacks *no cambian nada* en el bucle de entrenamiento. Inspeccionan el estado del bucle de entrenamiento y luego ejecutan alguna acción (detención anticipada, registro de resultados, etc.) según el estado. En otras palabras, un callback no puede usarse para implementar algo como una función de pérdida personalizada y necesitarás subclasificar y sobrescribir el método [`~Trainer.compute_loss`] para eso.
+
+Por ejemplo, si deseas agregar un callback de detención anticipada al bucle de entrenamiento después de 10 pasos.
+
+```py
+from transformers import TrainerCallback
+
+class EarlyStoppingCallback(TrainerCallback):
+ def __init__(self, num_steps=10):
+ self.num_steps = num_steps
+
+ def on_step_end(self, args, state, control, **kwargs):
+ if state.global_step >= self.num_steps:
+ return {"should_training_stop": True}
+ else:
+ return {}
+
+```
+Luego, pásalo al parámetro `callback` del [`Trainer`]:
+
+```py
+from transformers import Trainer
+
+trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=dataset["train"],
+ eval_dataset=dataset["test"],
+ processing_class=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics,
+ callback=[EarlyStoppingCallback()],
+)
+```
+
+## Logging
+
+
+
+Comprueba el API referencia [logging](./main_classes/logging) para mas información sobre los niveles differentes de logging.
+
+
+
+El [`Trainer`] está configurado a `logging.INFO` de forma predeterminada el cual informa errores, advertencias y otra información basica. Un [`Trainer`] réplica - en entornos distributos - está configurado a `logging.WARNING` el cual solamente informa errores y advertencias. Puedes cambiar el nivel de logging con los parametros [`log_level`](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.log_level) y [`log_level_replica`](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.log_level_replica) en [`TrainingArguments`].
+
+Para configurar el nivel de registro para cada nodo, usa el parámetro [`log_on_each_node`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.log_on_each_node) para determinar si deseas utilizar el nivel de registro en cada nodo o solo en el nodo principal.
+
+
+
+[`Trainer`] establece el nivel de registro por separado para cada nodo en el método [`Trainer.init`], por lo que es posible que desees considerar establecer esto antes si estás utilizando otras funcionalidades de Transformers antes de crear el objeto [`Trainer`].
+
+
+
+Por ejemplo, para establecer que tu código principal y los módulos utilicen el mismo nivel de registro según cada nodo:
+
+```py
+logger = logging.getLogger(__name__)
+
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+)
+
+log_level = training_args.get_process_log_level()
+logger.setLevel(log_level)
+datasets.utils.logging.set_verbosity(log_level)
+transformers.utils.logging.set_verbosity(log_level)
+
+trainer = Trainer(...)
+```
+
+
+
+Usa diferentes combinaciones de `log_level` y `log_level_replica` para configurar qué se registra en cada uno de los nodos.
+
+```bash
+my_app.py ... --log_level warning --log_level_replica error
+```
+
+
+
+
+Agrega el parámetro `log_on_each_node 0` para entornos multi-nodo.
+
+```bash
+my_app.py ... --log_level warning --log_level_replica error --log_on_each_node 0
+
+# set to only report errors
+my_app.py ... --log_level error --log_level_replica error --log_on_each_node 0
+```
+
+
+
+
+## NEFTune
+
+[NEFTune](https://hf.co/papers/2310.05914) es una técnica que puede mejorar el rendimiento al agregar ruido a los vectores de incrustación durante el entrenamiento. Para habilitarlo en [`Trainer`], establece el parámetro `neftune_noise_alpha` en [`TrainingArguments`] para controlar cuánto ruido se agrega.
+
+```py
+from transformers import TrainingArguments, Trainer
+
+training_args = TrainingArguments(..., neftune_noise_alpha=0.1)
+trainer = Trainer(..., args=training_args)
+```
+
+NEFTune se desactiva después del entrenamiento para restaurar la capa de incrustación original y evitar cualquier comportamiento inesperado.
+
+## Accelerate y Trainer
+
+La clase [`Trainer`] está impulsada por [Accelerate](https://hf.co/docs/accelerate), una biblioteca para entrenar fácilmente modelos de PyTorch en entornos distribuidos con soporte para integraciones como [FullyShardedDataParallel (FSDP)](https://pytorch.org/blog/introducing-pytorch-fully-sharded-data-parallel-api/) y [DeepSpeed](https://www.deepspeed.ai/).
+
+
+
+Aprende más sobre las estrategias de fragmentación FSDP, descarga de CPU y más con el [`Trainer`] en la guía [Paralela de Datos Completamente Fragmentados](fsdp).
+
+
+
+Para usar Accelerate con [`Trainer`], ejecuta el comando [`accelerate.config`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-config) para configurar el entrenamiento para tu entorno de entrenamiento. Este comando crea un `config_file.yaml` que se utilizará cuando inicies tu script de entrenamiento. Por ejemplo, algunas configuraciones de ejemplo que puedes configurar son:
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+distributed_type: MULTI_GPU
+downcast_bf16: 'no'
+gpu_ids: all
+machine_rank: 0 #change rank as per the node
+main_process_ip: 192.168.20.1
+main_process_port: 9898
+main_training_function: main
+mixed_precision: fp16
+num_machines: 2
+num_processes: 8
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+distributed_type: FSDP
+downcast_bf16: 'no'
+fsdp_config:
+ fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
+ fsdp_backward_prefetch_policy: BACKWARD_PRE
+ fsdp_forward_prefetch: true
+ fsdp_offload_params: false
+ fsdp_sharding_strategy: 1
+ fsdp_state_dict_type: FULL_STATE_DICT
+ fsdp_sync_module_states: true
+ fsdp_transformer_layer_cls_to_wrap: BertLayer
+ fsdp_use_orig_params: true
+machine_rank: 0
+main_training_function: main
+mixed_precision: bf16
+num_machines: 1
+num_processes: 2
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ deepspeed_config_file: /home/user/configs/ds_zero3_config.json
+ zero3_init_flag: true
+distributed_type: DEEPSPEED
+downcast_bf16: 'no'
+machine_rank: 0
+main_training_function: main
+num_machines: 1
+num_processes: 4
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ gradient_accumulation_steps: 1
+ gradient_clipping: 0.7
+ offload_optimizer_device: cpu
+ offload_param_device: cpu
+ zero3_init_flag: true
+ zero_stage: 2
+distributed_type: DEEPSPEED
+downcast_bf16: 'no'
+machine_rank: 0
+main_training_function: main
+mixed_precision: bf16
+num_machines: 1
+num_processes: 4
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+
+```
+
+
+
+
+El comando [`accelerate_launch`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-launch) es la forma recomendada de lanzar tu script de entrenamiento en un sistema distribuido con Accelerate y [`Trainer`] con los parámetros especificados en `config_file.yaml`. Este archivo se guarda en la carpeta de caché de Accelerate y se carga automáticamente cuando ejecutas `accelerate_launch`.
+
+Por ejemplo, para ejecutar el script de entrenamiento [`run_glue.py`](https://github.com/huggingface/transformers/blob/f4db565b695582891e43a5e042e5d318e28f20b8/examples/pytorch/text-classification/run_glue.py#L4) con la configuración de FSDP:
+
+```bash
+accelerate launch \
+ ./examples/pytorch/text-classification/run_glue.py \
+ --model_name_or_path bert-base-cased \
+ --task_name $TASK_NAME \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 16 \
+ --learning_rate 5e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/ \
+ --overwrite_output_dir
+```
+
+También puedes especificar los parámetros del archivo config_file.yaml directamente en la línea de comandos:
+
+```bash
+accelerate launch --num_processes=2 \
+ --use_fsdp \
+ --mixed_precision=bf16 \
+ --fsdp_auto_wrap_policy=TRANSFORMER_BASED_WRAP \
+ --fsdp_transformer_layer_cls_to_wrap="BertLayer" \
+ --fsdp_sharding_strategy=1 \
+ --fsdp_state_dict_type=FULL_STATE_DICT \
+ ./examples/pytorch/text-classification/run_glue.py
+ --model_name_or_path bert-base-cased \
+ --task_name $TASK_NAME \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 16 \
+ --learning_rate 5e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/ \
+ --overwrite_output_dir
+```
+
+Consulta el tutorial [Lanzamiento de tus scripts con Accelerate](https://huggingface.co/docs/accelerate/basic_tutorials/launch) para obtener más información sobre `accelerate_launch` y las configuraciones personalizadas.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/training.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/training.md
new file mode 100644
index 0000000000000000000000000000000000000000..f10f49d08997ac5f37b763c6b5f3cb284e400c88
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/es/training.md
@@ -0,0 +1,371 @@
+
+
+# Fine-tuning a un modelo pre-entrenado
+
+[[open-in-colab]]
+
+El uso de un modelo pre-entrenado tiene importantes ventajas. Reduce los costos de computación, la huella de carbono y te permite utilizar modelos de última generación sin tener que entrenar uno desde cero.
+
+* Fine-tuning a un modelo pre-entrenado con 🤗 Transformers [`Trainer`].
+* Fine-tuning a un modelo pre-entrenado en TensorFlow con Keras.
+* Fine-tuning a un modelo pre-entrenado en PyTorch nativo.
+
+
+
+Verás una advertencia acerca de que algunos de los pesos pre-entrenados no están siendo utilizados y que algunos pesos están siendo inicializados al azar. No te preocupes, esto es completamente normal.
+El head/cabezal pre-entrenado del modelo BERT se descarta y se sustituye por un head de clasificación inicializado aleatoriamente. Puedes aplicar fine-tuning a este nuevo head del modelo en tu tarea de clasificación de secuencias haciendo transfer learning del modelo pre-entrenado.
+
+
+
+### Hiperparámetros de entrenamiento
+
+A continuación, crea una clase [`TrainingArguments`] que contenga todos los hiperparámetros que puedes ajustar así como los indicadores para activar las diferentes opciones de entrenamiento. Para este tutorial puedes empezar con los [hiperparámetros](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments) de entrenamiento por defecto, pero siéntete libre de experimentar con ellos para encontrar tu configuración óptima.
+
+Especifica dónde vas a guardar los checkpoints de tu entrenamiento:
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(output_dir="test_trainer")
+```
+
+### Métricas
+
+El [`Trainer`] no evalúa automáticamente el rendimiento del modelo durante el entrenamiento. Tendrás que pasarle a [`Trainer`] una función para calcular y hacer un reporte de las métricas. La biblioteca de 🤗 Datasets proporciona una función de [`accuracy`](https://huggingface.co/metrics/accuracy) simple que puedes cargar con la función `load_metric` (ver este [tutorial](https://huggingface.co/docs/datasets/metrics) para más información):
+
+```py
+>>> import numpy as np
+>>> from datasets import load_metric
+
+>>> metric = load_metric("accuracy")
+```
+
+Define la función `compute` en `metric` para calcular el accuracy de tus predicciones. Antes de pasar tus predicciones a `compute`, necesitas convertir las predicciones a logits (recuerda que todos los modelos de 🤗 Transformers devuelven logits).
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... predictions = np.argmax(logits, axis=-1)
+... return metric.compute(predictions=predictions, references=labels)
+```
+
+Si quieres controlar tus métricas de evaluación durante el fine-tuning, especifica el parámetro `eval_strategy` en tus argumentos de entrenamiento para que el modelo tenga en cuenta la métrica de evaluación al final de cada época:
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(output_dir="test_trainer", eval_strategy="epoch")
+```
+
+### Trainer
+
+Crea un objeto [`Trainer`] con tu modelo, argumentos de entrenamiento, datasets de entrenamiento y de prueba, y tu función de evaluación:
+
+```py
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... )
+```
+
+A continuación, aplica fine-tuning a tu modelo llamando [`~transformers.Trainer.train`]:
+
+```py
+>>> trainer.train()
+```
+
+
+
+[`Trainer`] utiliza [`DataCollatorWithPadding`] por defecto por lo que no es necesario especificar explícitamente un intercalador de datos (data collator, en inglés).
+
+
+
+A continuación, convierte los datasets tokenizados en datasets de TensorFlow con el método [`to_tf_dataset`](https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.to_tf_dataset). Especifica tus entradas en `columns` y tu etiqueta en `label_cols`:
+
+```py
+>>> tf_train_dataset = small_train_dataset.to_tf_dataset(
+... columns=["attention_mask", "input_ids", "token_type_ids"],
+... label_cols="labels",
+... shuffle=True,
+... collate_fn=data_collator,
+... batch_size=8,
+... )
+
+>>> tf_validation_dataset = small_eval_dataset.to_tf_dataset(
+... columns=["attention_mask", "input_ids", "token_type_ids"],
+... label_cols="labels",
+... shuffle=False,
+... collate_fn=data_collator,
+... batch_size=8,
+... )
+```
+
+### Compila y ajusta
+
+Carguemos un modelo TensorFlow con el número esperado de labels:
+
+```py
+>>> import tensorflow as tf
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-cased", num_labels=5)
+```
+
+A continuación, compila y aplica fine-tuning a tu modelo con [`fit`](https://keras.io/api/models/model_training_apis/) como lo harías con cualquier otro modelo de Keras:
+
+```py
+>>> model.compile(
+... optimizer=tf.keras.optimizers.Adam(learning_rate=5e-5),
+... loss=tf.keras.losses.SparseCategoricalCrossentropy(from_logits=True),
+... metrics=tf.metrics.SparseCategoricalAccuracy(),
+... )
+
+>>> model.fit(tf_train_dataset, validation_data=tf_validation_dataset, epochs=3)
+```
+
+
+
+Consigue acceso gratuito a una GPU en la nube si es que no tienes este recurso de forma local con un notebook alojado en [Colaboratory](https://colab.research.google.com/) o [SageMaker StudioLab](https://studiolab.sagemaker.aws/).
+
+
+
+Genial, ¡ahora podemos entrenar! 🥳
+
+### Ciclo de entrenamiento
+
+Para hacer un seguimiento al progreso del entrenamiento, utiliza la biblioteca [tqdm](https://tqdm.github.io/) para añadir una barra de progreso sobre el número de pasos de entrenamiento:
+
+```py
+>>> from tqdm.auto import tqdm
+
+>>> progress_bar = tqdm(range(num_training_steps))
+
+>>> model.train()
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... outputs = model(**batch)
+... loss = outputs.loss
+... loss.backward()
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+### Métricas
+
+De la misma manera que necesitas añadir una función de evaluación al [`Trainer`], necesitas hacer lo mismo cuando escribas tu propio ciclo de entrenamiento. Pero en lugar de calcular y reportar la métrica al final de cada época, esta vez acumularás todos los batches con [`add_batch`](https://huggingface.co/docs/datasets/package_reference/main_classes?highlight=add_batch#datasets.Metric.add_batch) y calcularás la métrica al final.
+
+```py
+>>> metric = load_metric("accuracy")
+>>> model.eval()
+>>> for batch in eval_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... with torch.no_grad():
+... outputs = model(**batch)
+
+... logits = outputs.logits
+... predictions = torch.argmax(logits, dim=-1)
+... metric.add_batch(predictions=predictions, references=batch["labels"])
+
+>>> metric.compute()
+```
+
+
+
+Rappel, l'architecture fait référence au squelette du modèle et l'ensemble de poids contient les poids pour une architecture donnée. Par exemple, [BERT](https://huggingface.co/google-bert/bert-base-uncased) est une architecture, tandis que `google-bert/bert-base-uncased` est un ensemble de poids. Le terme modèle est général et peut signifier soit architecture soit ensemble de poids.
+
+
+
+Dans ce tutoriel, vous apprendrez à:
+
+ * Charger un tokenizer pré-entraîné.
+ * Charger un processeur d'image pré-entraîné.
+ * Charger un extracteur de caractéristiques pré-entraîné.
+ * Charger un processeur pré-entraîné.
+ * Charger un modèle pré-entraîné.
+
+## AutoTokenizer
+
+Quasiment toutes les tâches de traitement du langage (NLP) commencent avec un tokenizer. Un tokenizer convertit votre texte initial dans un format qui peut être traité par le modèle.
+
+Chargez un tokenizer avec [`AutoTokenizer.from_pretrained`]:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+```
+
+Puis, transformez votre texte initial comme montré ci-dessous:
+
+```py
+>>> sequence = "In a hole in the ground there lived a hobbit."
+>>> print(tokenizer(sequence))
+{'input_ids': [101, 1999, 1037, 4920, 1999, 1996, 2598, 2045, 2973, 1037, 7570, 10322, 4183, 1012, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+## AutoImageProcessor
+
+Pour les tâches de vision, un processeur d'image traite l'image pour la formater correctment.
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+```
+
+## AutoBackbone
+
+
+
+
Un backbone Swin avec plusieurs étapes pour produire une carte de caractéristiques.
+
+
+
Une carte de caractéristiques de la première étape du backbone. La partition de patch fait référence à la tige du modèle.
+
+
+Enfin, les classes `AutoModelFor` vous permettent de charger un modèle pré-entraîné pour une tâche donnée (voir [ici](model_doc/auto) pour une liste complète des tâches disponibles). Par exemple, chargez un modèle pour la classification de séquence avec [`AutoModelForSequenceClassification.from_pretrained`]:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Réutilisez facilement le même ensemble de poids pour charger une architecture pour une tâche différente :
+
+```py
+>>> from transformers import AutoModelForTokenClassification
+
+>>> model = AutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+Pour les modèles PyTorch, la fonction `from_pretrained()` utilise `torch.load()` qui utilise `pickle` en interne et est connu pour être non sécurisé. En général, ne chargez jamais un modèle qui pourrait provenir d'une source non fiable, ou qui pourrait avoir été altéré. Ce risque de sécurité est partiellement atténué pour les modèles hébergés publiquement sur le Hugging Face Hub, qui sont [scannés pour les logiciels malveillants](https://huggingface.co/docs/hub/security-malware) à chaque modification. Consultez la [documentation du Hub](https://huggingface.co/docs/hub/security) pour connaître les meilleures pratiques comme la [vérification des modifications signées](https://huggingface.co/docs/hub/security-gpg#signing-commits-with-gpg) avec GPG.
+
+Les points de contrôle TensorFlow et Flax ne sont pas concernés, et peuvent être chargés dans des architectures PyTorch en utilisant les arguments `from_tf` et `from_flax` de la fonction `from_pretrained` pour contourner ce problème.
+
+
+
+En général, nous recommandons d'utiliser les classes `AutoTokenizer` et `AutoModelFor` pour charger des instances pré-entraînées de tokenizers et modèles respectivement. Cela vous permettra de charger la bonne architecture à chaque fois. Dans le prochain [tutoriel](preprocessing), vous apprenez à utiliser un tokenizer, processeur d'image, extracteur de caractéristiques et processeur pour pré-traiter un jeu de données pour le fine-tuning.
+
+
+Enfin, les classes `TFAutoModelFor` vous permettent de charger un modèle pré-entraîné pour une tâche donnée (voir [ici](model_doc/auto) pour une liste complète des tâches disponibles). Par exemple, chargez un modèle pour la classification de séquence avec [`TFAutoModelForSequenceClassification.from_pretrained`]:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Réutilisez facilement le même ensemble de poids pour charger une architecture pour une tâche différente :
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+En général, nous recommandons d'utiliser les classes `AutoTokenizer` et `TFAutoModelFor` pour charger des instances pré-entraînées de tokenizers et modèles respectivement. Cela vous permettra de charger la bonne architecture à chaque fois. Dans le prochain [tutoriel](preprocessing), vous apprenez à utiliser un tokenizer, processeur d'image, extracteur de caractéristiques et processeur pour pré-traiter un jeu de données pour le fine-tuning.
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/in_translation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/in_translation.md
new file mode 100644
index 0000000000000000000000000000000000000000..910559ef6c9a0af10f6991c5464f52d4659f3426
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/in_translation.md
@@ -0,0 +1,5 @@
+
+
+# Traduction en cours.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/index.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/index.md
new file mode 100644
index 0000000000000000000000000000000000000000..51d35b76e877dbe80676c4e12508c36d16fd2a44
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/index.md
@@ -0,0 +1,412 @@
+
+
+# 🤗 Transformers
+
+Apprentissage automatique de pointe pour [PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/), et [JAX](https://jax.readthedocs.io/en/latest/).
+
+🤗 Transformers fournit des API et des outils pour télécharger et entraîner facilement des modèles pré-entraînés de pointe. L'utilisation de modèles pré-entraînés peut réduire vos coûts de calcul, votre empreinte carbone, et vous faire économiser le temps et les ressources nécessaires pour entraîner un modèle à partir de zéro. Ces modèles prennent en charge des tâches courantes dans différentes modalités, telles que :
+
+📝 **Traitement automatique des langues**: classification de texte, reconnaissance d'entités, système de question-réponse, modèle de langage, génération de résumé, traduction, question à choix multiples et génération de texte.
+
+
+## Contenu
+
+La documentation est organisée en 5 parties:
+
+- **DEMARRER** propose une visite rapide de la bibliothèque et des instructions d'installation pour être opérationnel.
+- **TUTORIELS** excellent point de départ pour les débutants. Cette section vous aidera à acquérir les compétences de base dont vous avez besoin pour commencer à utiliser la bibliothèque.
+- **GUIDES D'UTILISATION** pour différentes tâches comme par exemple le finetuning d'un modèle pré-entraîné pour la classification de texte ou comment créer et partager votre propre modèle.
+- **GUIDES CONCEPTUELS** pour plus de discussions et d'explications sur les concepts et les idées sous-jacentes aux modèles, aux tâches et à la philosophie de conception de 🤗 Transformers.
+- **API** décrit toutes les classes et fonctions :
+
+ - **CLASSES PRINCIPALES** détaille les classes les plus importantes comme la configuration, le modèle, le tokenizer et le pipeline..
+ - **MODELES** détaille les classes et les fonctions propres à chaque modèle de la bibliothèque.
+ - **UTILITAIRES INTERNES** détaille les classes et fonctions utilitaires utilisées en interne.
+
+### Modèles supportés
+
+
+
+1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
+1. **[ALIGN](model_doc/align)** (from Google Research) released with the paper [Scaling Up Visual and Vision-Language Representation Learning With Noisy Text Supervision](https://arxiv.org/abs/2102.05918) by Chao Jia, Yinfei Yang, Ye Xia, Yi-Ting Chen, Zarana Parekh, Hieu Pham, Quoc V. Le, Yunhsuan Sung, Zhen Li, Tom Duerig.
+1. **[AltCLIP](model_doc/altclip)** (from BAAI) released with the paper [AltCLIP: Altering the Language Encoder in CLIP for Extended Language Capabilities](https://arxiv.org/abs/2211.06679) by Chen, Zhongzhi and Liu, Guang and Zhang, Bo-Wen and Ye, Fulong and Yang, Qinghong and Wu, Ledell.
+1. **[Audio Spectrogram Transformer](model_doc/audio-spectrogram-transformer)** (from MIT) released with the paper [AST: Audio Spectrogram Transformer](https://arxiv.org/abs/2104.01778) by Yuan Gong, Yu-An Chung, James Glass.
+1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
+1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
+1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
+1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
+1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
+1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
+1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BioGpt](model_doc/biogpt)** (from Microsoft Research AI4Science) released with the paper [BioGPT: generative pre-trained transformer for biomedical text generation and mining](https://academic.oup.com/bib/advance-article/doi/10.1093/bib/bbac409/6713511?guestAccessKey=a66d9b5d-4f83-4017-bb52-405815c907b9) by Renqian Luo, Liai Sun, Yingce Xia, Tao Qin, Sheng Zhang, Hoifung Poon and Tie-Yan Liu.
+1. **[BiT](model_doc/bit)** (from Google AI) released with the paper [Big Transfer (BiT): General Visual Representation Learning](https://arxiv.org/abs/1912.11370) by Alexander Kolesnikov, Lucas Beyer, Xiaohua Zhai, Joan Puigcerver, Jessica Yung, Sylvain Gelly, Neil Houlsby.
+1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BLIP](model_doc/blip)** (from Salesforce) released with the paper [BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation](https://arxiv.org/abs/2201.12086) by Junnan Li, Dongxu Li, Caiming Xiong, Steven Hoi.
+1. **[BLOOM](model_doc/bloom)** (from BigScience workshop) released by the [BigScience Workshop](https://bigscience.huggingface.co/).
+1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499) by Adrian de Wynter and Daniel J. Perry.
+1. **[BridgeTower](model_doc/bridgetower)** (from Harbin Institute of Technology/Microsoft Research Asia/Intel Labs) released with the paper [BridgeTower: Building Bridges Between Encoders in Vision-Language Representation Learning](https://arxiv.org/abs/2206.08657) by Xiao Xu, Chenfei Wu, Shachar Rosenman, Vasudev Lal, Wanxiang Che, Nan Duan.
+1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
+1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
+1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
+1. **[Chinese-CLIP](model_doc/chinese_clip)** (from OFA-Sys) released with the paper [Chinese CLIP: Contrastive Vision-Language Pretraining in Chinese](https://arxiv.org/abs/2211.01335) by An Yang, Junshu Pan, Junyang Lin, Rui Men, Yichang Zhang, Jingren Zhou, Chang Zhou.
+1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
+1. **[CLIPSeg](model_doc/clipseg)** (from University of Göttingen) released with the paper [Image Segmentation Using Text and Image Prompts](https://arxiv.org/abs/2112.10003) by Timo Lüddecke and Alexander Ecker.
+1. **[CodeGen](model_doc/codegen)** (from Salesforce) released with the paper [A Conversational Paradigm for Program Synthesis](https://arxiv.org/abs/2203.13474) by Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Savarese, Caiming Xiong.
+1. **[Conditional DETR](model_doc/conditional_detr)** (from Microsoft Research Asia) released with the paper [Conditional DETR for Fast Training Convergence](https://arxiv.org/abs/2108.06152) by Depu Meng, Xiaokang Chen, Zejia Fan, Gang Zeng, Houqiang Li, Yuhui Yuan, Lei Sun, Jingdong Wang.
+1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
+1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
+1. **[CvT](model_doc/cvt)** (from Microsoft) released with the paper [CvT: Introducing Convolutions to Vision Transformers](https://arxiv.org/abs/2103.15808) by Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang.
+1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
+1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+1. **[Deformable DETR](model_doc/deformable_detr)** (from SenseTime Research) released with the paper [Deformable DETR: Deformable Transformers for End-to-End Object Detection](https://arxiv.org/abs/2010.04159) by Xizhou Zhu, Weijie Su, Lewei Lu, Bin Li, Xiaogang Wang, Jifeng Dai.
+1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
+1. **[DETA](model_doc/deta)** (from The University of Texas at Austin) released with the paper [NMS Strikes Back](https://arxiv.org/abs/2212.06137) by Jeffrey Ouyang-Zhang, Jang Hyun Cho, Xingyi Zhou, Philipp Krähenbühl.
+1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
+1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
+1. **[DiNAT](model_doc/dinat)** (from SHI Labs) released with the paper [Dilated Neighborhood Attention Transformer](https://arxiv.org/abs/2209.15001) by Ali Hassani and Humphrey Shi.
+1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) and a German version of DistilBERT.
+1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
+1. **[Donut](model_doc/donut)** (from NAVER), released together with the paper [OCR-free Document Understanding Transformer](https://arxiv.org/abs/2111.15664) by Geewook Kim, Teakgyu Hong, Moonbin Yim, Jeongyeon Nam, Jinyoung Park, Jinyeong Yim, Wonseok Hwang, Sangdoo Yun, Dongyoon Han, Seunghyun Park.
+1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
+1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+1. **[EfficientFormer](model_doc/efficientformer)** (from Snap Research) released with the paper [EfficientFormer: Vision Transformers at MobileNetSpeed](https://arxiv.org/abs/2206.01191) by Yanyu Li, Geng Yuan, Yang Wen, Ju Hu, Georgios Evangelidis, Sergey Tulyakov, Yanzhi Wang, Jian Ren.
+1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
+1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[ERNIE](model_doc/ernie)** (from Baidu) released with the paper [ERNIE: Enhanced Representation through Knowledge Integration](https://arxiv.org/abs/1904.09223) by Yu Sun, Shuohuan Wang, Yukun Li, Shikun Feng, Xuyi Chen, Han Zhang, Xin Tian, Danxiang Zhu, Hao Tian, Hua Wu.
+1. **[ESM](model_doc/esm)** (from Meta AI) are transformer protein language models. **ESM-1b** was released with the paper [Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118) by Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott, C. Lawrence Zitnick, Jerry Ma, and Rob Fergus. **ESM-1v** was released with the paper [Language models enable zero-shot prediction of the effects of mutations on protein function](https://doi.org/10.1101/2021.07.09.450648) by Joshua Meier, Roshan Rao, Robert Verkuil, Jason Liu, Tom Sercu and Alexander Rives. **ESM-2 and ESMFold** were released with the paper [Language models of protein sequences at the scale of evolution enable accurate structure prediction](https://doi.org/10.1101/2022.07.20.500902) by Zeming Lin, Halil Akin, Roshan Rao, Brian Hie, Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido, Alexander Rives.
+1. **[FastSpeech2Conformer](model_doc/fastspeech2_conformer)** (from ESPnet) released with the paper [Recent Developments On Espnet Toolkit Boosted By Conformer](https://arxiv.org/abs/2010.13956) by Pengcheng Guo, Florian Boyer, Xuankai Chang, Tomoki Hayashi, Yosuke Higuchi, Hirofumi Inaguma, Naoyuki Kamo, Chenda Li, Daniel Garcia-Romero, Jiatong Shi, Jing Shi, Shinji Watanabe, Kun Wei, Wangyou Zhang, and Yuekai Zhang.
+1. **[FLAN-T5](model_doc/flan-t5)** (from Google AI) released in the repository [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-t5-checkpoints) by Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V. Le, and Jason Wei
+1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
+1. **[FLAVA](model_doc/flava)** (from Facebook AI) released with the paper [FLAVA: A Foundational Language And Vision Alignment Model](https://arxiv.org/abs/2112.04482) by Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela.
+1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
+1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
+1. **[GIT](model_doc/git)** (from Microsoft Research) released with the paper [GIT: A Generative Image-to-text Transformer for Vision and Language](https://arxiv.org/abs/2205.14100) by Jianfeng Wang, Zhengyuan Yang, Xiaowei Hu, Linjie Li, Kevin Lin, Zhe Gan, Zicheng Liu, Ce Liu, Lijuan Wang.
+1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
+1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
+1. **[GPT NeoX](model_doc/gpt_neox)** (from EleutherAI) released with the paper [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://arxiv.org/abs/2204.06745) by Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach
+1. **[GPT NeoX Japanese](model_doc/gpt_neox_japanese)** (from ABEJA) released by Shinya Otani, Takayoshi Makabe, Anuj Arora, and Kyo Hattori.
+1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
+1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
+1. **[GPT-Sw3](model_doc/gpt-sw3)** (from AI-Sweden) released with the paper [Lessons Learned from GPT-SW3: Building the First Large-Scale Generative Language Model for Swedish](http://www.lrec-conf.org/proceedings/lrec2022/pdf/2022.lrec-1.376.pdf) by Ariel Ekgren, Amaru Cuba Gyllensten, Evangelia Gogoulou, Alice Heiman, Severine Verlinden, Joey Öhman, Fredrik Carlsson, Magnus Sahlgren.
+1. **[Graphormer](model_doc/graphormer)** (from Microsoft) released with the paper [Do Transformers Really Perform Bad for Graph Representation?](https://arxiv.org/abs/2106.05234) by Chengxuan Ying, Tianle Cai, Shengjie Luo, Shuxin Zheng, Guolin Ke, Di He, Yanming Shen, Tie-Yan Liu.
+1. **[GroupViT](model_doc/groupvit)** (from UCSD, NVIDIA) released with the paper [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://arxiv.org/abs/2202.11094) by Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang.
+1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
+1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
+1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
+1. **[Jukebox](model_doc/jukebox)** (from OpenAI) released with the paper [Jukebox: A Generative Model for Music](https://arxiv.org/pdf/2005.00341.pdf) by Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford, Ilya Sutskever.
+1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
+1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
+1. **[LayoutLMv3](model_doc/layoutlmv3)** (from Microsoft Research Asia) released with the paper [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://arxiv.org/abs/2204.08387) by Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
+1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
+1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LeViT](model_doc/levit)** (from Meta AI) released with the paper [LeViT: A Vision Transformer in ConvNet's Clothing for Faster Inference](https://arxiv.org/abs/2104.01136) by Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze.
+1. **[LiLT](model_doc/lilt)** (from South China University of Technology) released with the paper [LiLT: A Simple yet Effective Language-Independent Layout Transformer for Structured Document Understanding](https://arxiv.org/abs/2202.13669) by Jiapeng Wang, Lianwen Jin, Kai Ding.
+1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LongT5](model_doc/longt5)** (from Google AI) released with the paper [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://arxiv.org/abs/2112.07916) by Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung, Yinfei Yang.
+1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
+1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490) by Hao Tan and Mohit Bansal.
+1. **[M-CTC-T](model_doc/mctct)** (from Facebook) released with the paper [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://arxiv.org/abs/2111.00161) by Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert.
+1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
+1. **[MarkupLM](model_doc/markuplm)** (from Microsoft Research Asia) released with the paper [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document Understanding](https://arxiv.org/abs/2110.08518) by Junlong Li, Yiheng Xu, Lei Cui, Furu Wei.
+1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
+1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
+1. **[mBART](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+1. **[mBART-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
+1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
+1. **[MobileBERT](model_doc/mobilebert)** (from CMU/Google Brain) released with the paper [MobileBERT: a Compact Task-Agnostic BERT for Resource-Limited Devices](https://arxiv.org/abs/2004.02984) by Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny Zhou.
+1. **[MobileNetV1](model_doc/mobilenet_v1)** (from Google Inc.) released with the paper [MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications](https://arxiv.org/abs/1704.04861) by Andrew G. Howard, Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, Marco Andreetto, Hartwig Adam.
+1. **[MobileNetV2](model_doc/mobilenet_v2)** (from Google Inc.) released with the paper [MobileNetV2: Inverted Residuals and Linear Bottlenecks](https://arxiv.org/abs/1801.04381) by Mark Sandler, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, Liang-Chieh Chen.
+1. **[MobileViT](model_doc/mobilevit)** (from Apple) released with the paper [MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer](https://arxiv.org/abs/2110.02178) by Sachin Mehta and Mohammad Rastegari.
+1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
+1. **[MVP](model_doc/mvp)** (from RUC AI Box) released with the paper [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://arxiv.org/abs/2206.12131) by Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen.
+1. **[NAT](model_doc/nat)** (from SHI Labs) released with the paper [Neighborhood Attention Transformer](https://arxiv.org/abs/2204.07143) by Ali Hassani, Steven Walton, Jiachen Li, Shen Li, and Humphrey Shi.
+1. **[Nezha](model_doc/nezha)** (from Huawei Noah’s Ark Lab) released with the paper [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://arxiv.org/abs/1909.00204) by Junqiu Wei, Xiaozhe Ren, Xiaoguang Li, Wenyong Huang, Yi Liao, Yasheng Wang, Jiashu Lin, Xin Jiang, Xiao Chen and Qun Liu.
+1. **[NLLB](model_doc/nllb)** (from Meta) released with the paper [No Language Left Behind: Scaling Human-Centered Machine Translation](https://arxiv.org/abs/2207.04672) by the NLLB team.
+1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
+1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
+1. **[OPT](master/model_doc/opt)** (from Meta AI) released with the paper [OPT: Open Pre-trained Transformer Language Models](https://arxiv.org/abs/2205.01068) by Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al.
+1. **[OWL-ViT](model_doc/owlvit)** (from Google AI) released with the paper [Simple Open-Vocabulary Object Detection with Vision Transformers](https://arxiv.org/abs/2205.06230) by Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby.
+1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
+1. **[PEGASUS-X](model_doc/pegasus_x)** (from Google) released with the paper [Investigating Efficiently Extending Transformers for Long Input Summarization](https://arxiv.org/abs/2208.04347) by Jason Phang, Yao Zhao, and Peter J. Liu.
+1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
+1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
+1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
+1. **[RAG](model_doc/rag)** (from Facebook) released with the paper [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://arxiv.org/abs/2005.11401) by Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela.
+1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
+1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://arxiv.org/abs/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
+1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
+1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
+1. **[RoBERTa-PreLayerNorm](model_doc/roberta-prelayernorm)** (from Facebook) released with the paper [fairseq: A Fast, Extensible Toolkit for Sequence Modeling](https://arxiv.org/abs/1904.01038) by Myle Ott, Sergey Edunov, Alexei Baevski, Angela Fan, Sam Gross, Nathan Ng, David Grangier, Michael Auli.
+1. **[RoCBert](model_doc/roc_bert)** (from WeChatAI) released with the paper [RoCBert: Robust Chinese Bert with Multimodal Contrastive Pretraining](https://aclanthology.org/2022.acl-long.65.pdf) by HuiSu, WeiweiShi, XiaoyuShen, XiaoZhou, TuoJi, JiaruiFang, JieZhou.
+1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
+1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
+1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SpeechT5](model_doc/speecht5)** (from Microsoft Research) released with the paper [SpeechT5: Unified-Modal Encoder-Decoder Pre-Training for Spoken Language Processing](https://arxiv.org/abs/2110.07205) by Junyi Ao, Rui Wang, Long Zhou, Chengyi Wang, Shuo Ren, Yu Wu, Shujie Liu, Tom Ko, Qing Li, Yu Zhang, Zhihua Wei, Yao Qian, Jinyu Li, Furu Wei.
+1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
+1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
+1. **[SqueezeBERT](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
+1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+1. **[Swin Transformer V2](model_doc/swinv2)** (from Microsoft) released with the paper [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883) by Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo.
+1. **[Swin2SR](model_doc/swin2sr)** (from University of Würzburg) released with the paper [Swin2SR: SwinV2 Transformer for Compressed Image Super-Resolution and Restoration](https://arxiv.org/abs/2209.11345) by Marcos V. Conde, Ui-Jin Choi, Maxime Burchi, Radu Timofte.
+1. **[SwitchTransformers](model_doc/switch_transformers)** (from Google) released with the paper [Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity](https://arxiv.org/abs/2101.03961) by William Fedus, Barret Zoph, Noam Shazeer.
+1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[Table Transformer](model_doc/table-transformer)** (from Microsoft Research) released with the paper [PubTables-1M: Towards Comprehensive Table Extraction From Unstructured Documents](https://arxiv.org/abs/2110.00061) by Brandon Smock, Rohith Pesala, Robin Abraham.
+1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
+1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
+1. **[Time Series Transformer](model_doc/time_series_transformer)** (from HuggingFace).
+1. **[TimeSformer](model_doc/timesformer)** (from Facebook) released with the paper [Is Space-Time Attention All You Need for Video Understanding?](https://arxiv.org/abs/2102.05095) by Gedas Bertasius, Heng Wang, Lorenzo Torresani.
+1. **[Trajectory Transformer](model_doc/trajectory_transformers)** (from the University of California at Berkeley) released with the paper [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://arxiv.org/abs/2106.02039) by Michael Janner, Qiyang Li, Sergey Levine
+1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
+1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
+1. **[UL2](model_doc/ul2)** (from Google Research) released with the paper [Unifying Language Learning Paradigms](https://arxiv.org/abs/2205.05131v1) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler
+1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
+1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
+1. **[UPerNet](model_doc/upernet)** (from Peking University) released with the paper [Unified Perceptual Parsing for Scene Understanding](https://arxiv.org/abs/1807.10221) by Tete Xiao, Yingcheng Liu, Bolei Zhou, Yuning Jiang, Jian Sun.
+1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://arxiv.org/abs/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+1. **[VideoMAE](model_doc/videomae)** (from Multimedia Computing Group, Nanjing University) released with the paper [VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training](https://arxiv.org/abs/2203.12602) by Zhan Tong, Yibing Song, Jue Wang, Limin Wang.
+1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
+1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
+1. **[ViT Hybrid](model_doc/vit_hybrid)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
+1. **[ViTMSN](model_doc/vit_msn)** (from Meta AI) released with the paper [Masked Siamese Networks for Label-Efficient Learning](https://arxiv.org/abs/2204.07141) by Mahmoud Assran, Mathilde Caron, Ishan Misra, Piotr Bojanowski, Florian Bordes, Pascal Vincent, Armand Joulin, Michael Rabbat, Nicolas Ballas.
+1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
+1. **[Wav2Vec2-Conformer](model_doc/wav2vec2-conformer)** (from Facebook AI) released with the paper [FAIRSEQ S2T: Fast Speech-to-Text Modeling with FAIRSEQ](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Sravya Popuri, Dmytro Okhonko, Juan Pino.
+1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
+1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
+1. **[Whisper](model_doc/whisper)** (from OpenAI) released with the paper [Robust Speech Recognition via Large-Scale Weak Supervision](https://cdn.openai.com/papers/whisper.pdf) by Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever.
+1. **[X-CLIP](model_doc/xclip)** (from Microsoft Research) released with the paper [Expanding Language-Image Pretrained Models for General Video Recognition](https://arxiv.org/abs/2208.02816) by Bolin Ni, Houwen Peng, Minghao Chen, Songyang Zhang, Gaofeng Meng, Jianlong Fu, Shiming Xiang, Haibin Ling.
+1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
+1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291) by Guillaume Lample and Alexis Conneau.
+1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
+1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
+1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
+1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
+1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
+1. **[YOLOS](model_doc/yolos)** (from Huazhong University of Science & Technology) released with the paper [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://arxiv.org/abs/2106.00666) by Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu.
+1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
+
+
+### Frameworks compatibles
+
+Le tableau ci-dessous représente la prise en charge actuelle dans la bibliothèque pour chacun de ces modèles, qu'ils aient ou non un tokenizer Python (appelé "slow"). Un tokenizer rapide ("fast") soutenu par la bibliothèque 🤗 Tokenizers, qu'ils aient un support en Jax (via Flax), PyTorch, et/ou TensorFlow.
+
+
+
+| Modèle | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:-----------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| AltCLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Audio Spectrogram Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBird-Pegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BioGpt | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BiT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BLOOM | ❌ | ✅ | ✅ | ❌ | ❌ |
+| BridgeTower | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| CANINE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Chinese-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CLIPSeg | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CodeGen | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Conditional DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNeXT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| CvT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Deformable DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DETA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DiNAT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DonutSwin | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| EfficientFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ERNIE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ESM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FastSpeech2Conformer | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FLAVA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GIT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
+| GPT NeoX Japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| GPT-Sw3 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Graphormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GroupViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Jukebox | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LayoutLMv3 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LeViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LiLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LongT5 | ❌ | ❌ | ✅ | ❌ | ✅ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M-CTC-T | ❌ | ❌ | ✅ | ❌ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MarkupLM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Mask2Former | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MaskFormerSwin | ❌ | ❌ | ❌ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Megatron-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MobileNetV1 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileNetV2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MVP | ✅ | ✅ | ✅ | ❌ | ❌ |
+| NAT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Nezha | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Nyströmformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OneFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| OPT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| OWL-ViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| PEGASUS-X | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| REALM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ✅ | ❌ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoBERTa-PreLayerNorm | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RoCBert | ✅ | ❌ | ✅ | ❌ | ❌ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| SegFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| SpeechT5 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Swin Transformer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Swin Transformer V2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Swin2SR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SwitchTransformers | ❌ | ❌ | ✅ | ❌ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Table Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Time Series Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TimeSformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UPerNet | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VideoMAE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| VisualBERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViT Hybrid | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| ViTMSN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Whisper | ✅ | ❌ | ✅ | ✅ | ❌ |
+| X-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/installation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/installation.md
new file mode 100644
index 0000000000000000000000000000000000000000..da3e585df7aee38ae672fa46c6913b867c3d5c2f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/installation.md
@@ -0,0 +1,258 @@
+
+
+# Installation
+
+Installez 🤗 Transformers pour n'importe quelle librairie d'apprentissage profond avec laquelle vous avez l'habitude de travaillez, configurez votre cache et configurez 🤗 Transformers pour un usage hors ligne (facultatif).
+
+🤗 Transformers est testé avec Python 3.6+, PyTorch 1.1.0+, TensorFlow 2.0+ et Flax.
+Consulter les instructions d'installation ci-dessous pour la librairie d'apprentissage profond que vous utilisez:
+
+ * Instructions d'installation pour [PyTorch](https://pytorch.org/get-started/locally/).
+ * Instructions d'installation pour [TensorFlow 2.0](https://www.tensorflow.org/install/pip).
+ * Instructions d'installation pour [Flax](https://flax.readthedocs.io/en/latest/).
+
+## Installation avec pip
+
+Vous devriez installer 🤗 Transformers dans un [environnement virtuel](https://docs.python.org/3/library/venv.html).
+Si vous n'êtes pas à l'aise avec les environnements virtuels, consultez ce [guide](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/).
+Utiliser un environnement virtuel permet de facilement gérer différents projets et d'éviter des erreurs de compatibilité entre les différentes dépendances.
+
+Commencez par créer un environnement virtuel dans l'espace de travail de votre projet :
+
+```bash
+python -m venv .env
+```
+
+Activez l'environnement virtuel. Sur Linux ou MacOs :
+
+```bash
+source .env/bin/activate
+```
+
+Activez l'environnement virtuel sur Windows :
+
+```bash
+.env/Scripts/activate
+```
+
+Maintenant, 🤗 Transformers peut être installé avec la commande suivante :
+
+```bash
+pip install transformers
+```
+
+Pour une utilisation avec CPU seulement, 🤗 Transformers et la librairie d'apprentissage profond de votre choix peuvent être installés en une seule ligne.
+Par exemple, installez 🤗 Transformers et PyTorch avec la commande suivante :
+
+```bash
+pip install 'transformers[torch]'
+```
+
+🤗 Transformers et TensorFlow 2.0 :
+
+```bash
+pip install 'transformers[tf-cpu]'
+```
+
+
+
+Pour les architectures mac M1 / ARM
+
+Vous devez installer les outils suivants avant d'installer TensorFLow 2.0
+
+```bash
+brew install cmake
+brew install pkg-config
+```
+
+
+
+🤗 Transformers et Flax :
+
+```bash
+pip install 'transformers[flax]'
+```
+
+Vérifiez que 🤗 Transformers a bien été installé avec la commande suivante. La commande va télécharger un modèle pré-entraîné :
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('we love you'))"
+```
+
+Le label et score sont ensuite affichés :
+
+```bash
+[{'label': 'POSITIVE', 'score': 0.9998704791069031}]
+```
+
+## Installation depuis le code source
+
+Installez 🤗 Transformers depuis le code source avec la commande suivante :
+
+```bash
+pip install git+https://github.com/huggingface/transformers
+```
+
+Cette commande installe la version depuis la branche `main` au lieu de la dernière version stable. La version de la branche `main` est utile pour avoir les derniers développements. Par exemple, si un bug a été résolu depuis la dernière version stable mais n'a pas encore été publié officiellement. Cependant, cela veut aussi dire que la version de la branche `main` n'est pas toujours stable. Nous nous efforçons de maintenir la version de la branche `main` opérationnelle, et la plupart des problèmes sont généralement résolus en l'espace de quelques heures ou d'un jour. Si vous recontrez un problème, n'hésitez pas à créer une [Issue](https://github.com/huggingface/transformers/issues) pour que l'on puisse trouver une solution au plus vite !
+
+Vérifiez que 🤗 Transformers a bien été installé avec la commande suivante :
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('I love you'))"
+```
+
+## Installation modifiable
+
+Vous aurez besoin d'une installation modifiable si vous le souhaitez :
+
+ * Utiliser la version de la branche `main` du code source.
+ * Contribuer à 🤗 Transformers et vouler tester vos modifications du code source.
+
+Clonez le projet et installez 🤗 Transformers avec les commandes suivantes :
+
+```bash
+git clone https://github.com/huggingface/transformers.git
+cd transformers
+pip install -e .
+```
+
+Ces commandes créent des liens entre le dossier où le projet a été cloné et les chemins de vos librairies Python. Python regardera maintenant dans le dossier que vous avez cloné en plus des dossiers où sont installées vos autres librairies. Par exemple, si vos librairies Python sont installées dans `~/anaconda3/envs/main/lib/python3.7/site-packages/`, Python cherchera aussi dans le dossier où vous avez cloné : `~/transformers/`.
+
+
+
+Vous devez garder le dossier `transformers` si vous voulez continuer d'utiliser la librairie.
+
+
+
+Maintenant, vous pouvez facilement mettre à jour votre clone avec la dernière version de 🤗 Transformers en utilisant la commande suivante :
+
+```bash
+cd ~/transformers/
+git pull
+```
+
+Votre environnement Python utilisera la version de la branche `main` lors de la prochaine exécution.
+
+## Installation avec conda
+
+Installation via le canal `conda-forge` de conda :
+
+```bash
+conda install conda-forge::transformers
+```
+
+## Configuration du cache
+
+Les modèles pré-entraînés sont téléchargés et mis en cache localement dans le dossier suivant : `~/.cache/huggingface/hub`. C'est le dossier par défaut donné par la variable d'environnement `TRANSFORMERS_CACHE`. Sur Windows, le dossier par défaut est `C:\Users\nom_utilisateur\.cache\huggingface\hub`. Vous pouvez modifier les variables d'environnement indiquées ci-dessous - par ordre de priorité - pour spécifier un dossier de cache différent :
+
+1. Variable d'environnement (par défaut) : `HF_HUB_CACHE` ou `TRANSFORMERS_CACHE`.
+2. Variable d'environnement : `HF_HOME`.
+3. Variable d'environnement : `XDG_CACHE_HOME` + `/huggingface`.
+
+
+
+🤗 Transformers utilisera les variables d'environnement `PYTORCH_TRANSFORMERS_CACHE` ou `PYTORCH_PRETRAINED_BERT_CACHE` si vous utilisez une version précédente de cette librairie et avez défini ces variables d'environnement, sauf si vous spécifiez la variable d'environnement `TRANSFORMERS_CACHE`.
+
+
+
+## Mode hors ligne
+
+🤗 Transformers peut fonctionner dans un environnement cloisonné ou hors ligne en n'utilisant que des fichiers locaux. Définissez la variable d'environnement `HF_HUB_OFFLINE=1` pour activer ce mode.
+
+
+
+Ajoutez [🤗 Datasets](https://huggingface.co/docs/datasets/) à votre processus d'entraînement hors ligne en définissant la variable d'environnement `HF_DATASETS_OFFLINE=1`.
+
+
+
+```bash
+HF_DATASETS_OFFLINE=1 HF_HUB_OFFLINE=1 \
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+Le script devrait maintenant s'exécuter sans rester en attente ou attendre une expiration, car il n'essaiera pas de télécharger des modèle sur le Hub.
+
+Vous pouvez aussi éviter de télécharger un modèle à chaque appel de la fonction [`~PreTrainedModel.from_pretrained`] en utilisant le paramètre [local_files_only]. Seuls les fichiers locaux sont chargés lorsque ce paramètre est activé (c.-à-d. `local_files_only=True`) :
+
+```py
+from transformers import T5Model
+
+model = T5Model.from_pretrained("./path/to/local/directory", local_files_only=True)
+```
+
+### Récupérer des modèles et des tokenizers pour une utilisation hors ligne
+
+Une autre option pour utiliser 🤗 Transformers hors ligne est de télécharger les fichiers à l'avance, puis d'utiliser les chemins locaux lorsque vous en avez besoin en mode hors ligne. Il existe trois façons de faire cela :
+
+ * Téléchargez un fichier via l'interface utilisateur sur le [Model Hub](https://huggingface.co/models) en cliquant sur l'icône ↓.
+
+ 
+
+ * Utilisez les fonctions [`PreTrainedModel.from_pretrained`] et [`PreTrainedModel.save_pretrained`] :
+
+ 1. Téléchargez vos fichiers à l'avance avec [`PreTrainedModel.from_pretrained`]:
+
+ ```py
+ >>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("bigscience/T0_3B")
+ >>> model = AutoModelForSeq2SeqLM.from_pretrained("bigscience/T0_3B")
+ ```
+
+ 2. Sauvegardez les fichiers dans un dossier de votre choix avec [`PreTrainedModel.save_pretrained`]:
+
+ ```py
+ >>> tokenizer.save_pretrained("./your/path/bigscience_t0")
+ >>> model.save_pretrained("./your/path/bigscience_t0")
+ ```
+
+ 3. Maintenant, lorsque vous êtes hors ligne, rechargez vos fichiers avec [`PreTrainedModel.from_pretrained`] depuis le dossier où vous les avez sauvegardés :
+
+ ```py
+ >>> tokenizer = AutoTokenizer.from_pretrained("./your/path/bigscience_t0")
+ >>> model = AutoModel.from_pretrained("./your/path/bigscience_t0")
+ ```
+
+ * Téléchargez des fichiers de manière automatique avec la librairie [huggingface_hub](https://github.com/huggingface/huggingface_hub/tree/main/src/huggingface_hub) :
+
+ 1. Installez la librairie `huggingface_hub` dans votre environnement virtuel :
+
+ ```bash
+ python -m pip install huggingface_hub
+ ```
+
+ 2. Utilisez la fonction [`hf_hub_download`](https://huggingface.co/docs/hub/adding-a-library#download-files-from-the-hub) pour télécharger un fichier vers un chemin de votre choix. Par exemple, la commande suivante télécharge le fichier `config.json` du modèle [T0](https://huggingface.co/bigscience/T0_3B) vers le chemin de votre choix :
+
+ ```py
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> hf_hub_download(repo_id="bigscience/T0_3B", filename="config.json", cache_dir="./your/path/bigscience_t0")
+ ```
+
+Une fois que votre fichier est téléchargé et caché localement, spécifiez son chemin local pour le charger et l'utiliser :
+
+```py
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("./your/path/bigscience_t0/config.json")
+```
+
+
+
+Consultez la section [How to download files from the Hub (Comment télécharger des fichiers depuis le Hub)](https://huggingface.co/docs/hub/how-to-downstream) pour plus de détails sur le téléchargement de fichiers stockés sur le Hub.
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/quicktour.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/quicktour.md
new file mode 100644
index 0000000000000000000000000000000000000000..dcf21562316d5d1d1991a098f0ef039b5b62372d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/quicktour.md
@@ -0,0 +1,550 @@
+
+
+# Visite rapide
+
+[[open-in-colab]]
+
+Soyez opérationnel avec 🤗 Transformers ! Que vous soyez un développeur ou un utilisateur lambda, cette visite rapide vous aidera à démarrer et vous montrera comment utiliser le [`pipeline`] pour l'inférence, charger un modèle pré-entraîné et un préprocesseur avec une [AutoClass](./model_doc/auto), et entraîner rapidement un modèle avec PyTorch ou TensorFlow. Si vous êtes un débutant, nous vous recommandons de consulter nos tutoriels ou notre [cours](https://huggingface.co/course/chapter1/1) suivant pour des explications plus approfondies des concepts présentés ici.
+
+Avant de commencer, assurez-vous que vous avez installé toutes les bibliothèques nécessaires :
+
+```bash
+!pip install transformers datasets evaluate accelerate
+```
+
+Vous aurez aussi besoin d'installer votre bibliothèque d'apprentissage profond favorite :
+
+
+
+
+```bash
+pip install torch
+```
+
+
+
+```bash
+pip install tensorflow
+```
+
+
+
+## Pipeline
+
+
+
+Utilisez [`AutoModelForSequenceClassification`] et [`AutoTokenizer`] pour charger le modèle pré-entraîné et le tokenizer adapté (plus de détails sur une `AutoClass` dans la section suivante) :
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+Utilisez [`TFAutoModelForSequenceClassification`] et [`AutoTokenizer`] pour charger le modèle pré-entraîné et le tokenizer adapté (plus de détails sur une `TFAutoClass` dans la section suivante) :
+
+```py
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+Spécifiez le modèle et le tokenizer dans le [`pipeline`], et utilisez le `classifier` sur le texte en français :
+
+```py
+>>> classifier = pipeline("sentiment-analysis", model=model, tokenizer=tokenizer)
+>>> classifier("Nous sommes très heureux de vous présenter la bibliothèque 🤗 Transformers.")
+[{'label': '5 stars', 'score': 0.7273}]
+```
+
+Si vous ne parvenez pas à trouver un modèle adapté à votre cas d'utilisation, vous devrez finetuner un modèle pré-entraîné sur vos données. Jetez un coup d'œil à notre [tutoriel sur le finetuning](./training) pour apprendre comment faire. Enfin, après avoir finetuné votre modèle pré-entraîné, pensez à [partager](./model_sharing) le modèle avec la communauté sur le Hub afin de démocratiser l'apprentissage automatique pour tous ! 🤗
+
+## AutoClass
+
+
+
+
+```py
+>>> pt_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="pt",
+... )
+```
+
+
+
+```py
+>>> tf_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="tf",
+... )
+```
+
+
+
+
+
+Consultez le tutoriel [prétraitement](./preprocessing) pour plus de détails sur la tokenisation, et sur la manière d'utiliser un [`AutoImageProcessor`], un [`AutoFeatureExtractor`] et un [`AutoProcessor`] pour prétraiter les images, l'audio et les contenus multimodaux.
+
+
+
+### AutoModel
+
+
+
+🤗 Transformers fournit un moyen simple et unifié de charger des instances pré-entraînées. Cela signifie que vous pouvez charger un [`AutoModel`] comme vous chargeriez un [`AutoTokenizer`]. La seule différence est de sélectionner l'[`AutoModel`] approprié pour la tâche. Pour une classification de texte (ou de séquence de textes), vous devez charger [`AutoModelForSequenceClassification`] :
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+Voir le [résumé de la tâche](./task_summary) pour vérifier si elle est prise en charge par une classe [`AutoModel`].
+
+
+
+Maintenant, passez votre échantillon d'entrées prétraitées directement au modèle. Il vous suffit de décompresser le dictionnaire en ajoutant `**` :
+
+```py
+>>> pt_outputs = pt_model(**pt_batch)
+```
+
+Le modèle produit les activations finales dans l'attribut `logits`. Appliquez la fonction softmax aux `logits` pour récupérer les probabilités :
+
+```py
+>>> from torch import nn
+
+>>> pt_predictions = nn.functional.softmax(pt_outputs.logits, dim=-1)
+>>> print(pt_predictions)
+tensor([[0.0021, 0.0018, 0.0115, 0.2121, 0.7725],
+ [0.2084, 0.1826, 0.1969, 0.1755, 0.2365]], grad_fn=)
+```
+
+
+🤗 Transformers fournit un moyen simple et unifié de charger des instances pré-entraînés. Cela signifie que vous pouvez charger un [`TFAutoModel`] comme vous chargeriez un [`AutoTokenizer`]. La seule différence est de sélectionner le [`TFAutoModel`] approprié pour la tâche. Pour une classification de texte (ou de séquence de textes), vous devez charger [`TFAutoModelForSequenceClassification`] :
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+Voir le [résumé de la tâche](./task_summary) pour vérifier si elle est prise en charge par une classe [`AutoModel`].
+
+
+
+Passez maintenant votre échantillon d'entrées prétraitées directement au modèle en passant les clés du dictionnaire directement aux tensors :
+
+```py
+>>> tf_outputs = tf_model(tf_batch)
+```
+
+Le modèle produit les activations finales dans l'attribut `logits`. Appliquez la fonction softmax aux `logits` pour récupérer les probabilités :
+
+```py
+>>> import tensorflow as tf
+
+>>> tf_predictions = tf.nn.softmax(tf_outputs.logits, axis=-1)
+>>> tf_predictions # doctest: +IGNORE_RESULT
+```
+
+
+
+
+
+Tous les modèles 🤗 Transformers (PyTorch ou TensorFlow) produisent les tensors *avant* la fonction d'activation finale (comme softmax) car la fonction d'activation finale est souvent fusionnée avec le calcul de la perte. Les structures produites par le modèle sont des classes de données spéciales, de sorte que leurs attributs sont autocomplétés dans un environnement de développement. Les structures produites par le modèle se comportent comme un tuple ou un dictionnaire (vous pouvez les indexer avec un entier, une tranche ou une chaîne), auquel cas les attributs qui sont None sont ignorés.
+
+
+
+### Sauvegarder un modèle
+
+
+
+Une fois que votre modèle est finetuné, vous pouvez le sauvegarder avec son tokenizer en utilisant [`PreTrainedModel.save_pretrained`] :
+
+```py
+>>> pt_save_directory = "./pt_save_pretrained"
+>>> tokenizer.save_pretrained(pt_save_directory) # doctest: +IGNORE_RESULT
+>>> pt_model.save_pretrained(pt_save_directory)
+```
+
+Lorsque vous voulez réutiliser le modèle, rechargez-le avec [`PreTrainedModel.from_pretrained`] :
+
+```py
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("./pt_save_pretrained")
+```
+
+
+Une fois que votre modèle est finetuné, vous pouvez le sauvegarder avec son tokenizer en utilisant [`TFPreTrainedModel.save_pretrained`] :
+
+```py
+>>> tf_save_directory = "./tf_save_pretrained"
+>>> tokenizer.save_pretrained(tf_save_directory) # doctest: +IGNORE_RESULT
+>>> tf_model.save_pretrained(tf_save_directory)
+```
+
+Lorsque vous voulez réutiliser le modèle, rechargez-le avec [`TFPreTrainedModel.from_pretrained`] :
+
+```py
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("./tf_save_pretrained")
+```
+
+
+
+Une fonctionnalité particulièrement cool 🤗 Transformers est la possibilité d'enregistrer un modèle et de le recharger en tant que modèle PyTorch ou TensorFlow. Le paramètre `from_pt` ou `from_tf` permet de convertir le modèle d'un framework à l'autre :
+
+
+
+
+```py
+>>> from transformers import AutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(pt_save_directory)
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(pt_save_directory, from_pt=True)
+```
+
+
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(tf_save_directory)
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(tf_save_directory, from_tf=True)
+```
+
+
+
+## Constructions de modèles personnalisés
+
+Vous pouvez modifier la configuration du modèle pour changer la façon dont un modèle est construit. La configuration spécifie les attributs d'un modèle, tels que le nombre de couches ou de têtes d'attention. Vous partez de zéro lorsque vous initialisez un modèle à partir d'une configuration personnalisée. Les attributs du modèle sont initialisés de manière aléatoire et vous devrez entraîner le modèle avant de pouvoir l'utiliser pour obtenir des résultats significatifs.
+
+Commencez par importer [`AutoConfig`], puis chargez le modèle pré-entraîné que vous voulez modifier. Dans [`AutoConfig.from_pretrained`], vous pouvez spécifier l'attribut que vous souhaitez modifier, tel que le nombre de têtes d'attention :
+
+```py
+>>> from transformers import AutoConfig
+
+>>> my_config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased", n_heads=12)
+```
+
+
+
+Créez un modèle personnalisé à partir de votre configuration avec [`AutoModel.from_config`] :
+
+```py
+>>> from transformers import AutoModel
+
+>>> my_model = AutoModel.from_config(my_config)
+```
+
+
+Créez un modèle personnalisé à partir de votre configuration avec [`TFAutoModel.from_config`] :
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> my_model = TFAutoModel.from_config(my_config)
+```
+
+
+
+Consultez le guide [Créer une architecture personnalisée](./create_a_model) pour plus d'informations sur la création de configurations personnalisées.
+
+## Trainer - une boucle d'entraînement optimisée par PyTorch
+
+Tous les modèles sont des [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) standard, vous pouvez donc les utiliser dans n'importe quelle boucle d'entraînement typique. Bien que vous puissiez écrire votre propre boucle d'entraînement, 🤗 Transformers fournit une classe [`Trainer`] pour PyTorch, qui contient la boucle d'entraînement de base et ajoute des fonctionnalités supplémentaires comme l'entraînement distribué, la précision mixte, et plus encore.
+
+En fonction de votre tâche, vous passerez généralement les paramètres suivants à [`Trainer`] :
+
+1. Un [`PreTrainedModel`] ou un [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module):
+
+ ```py
+ >>> from transformers import AutoModelForSequenceClassification
+
+ >>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. [`TrainingArguments`] contient les hyperparamètres du modèle que vous pouvez changer comme le taux d'apprentissage, la taille de l'échantillon, et le nombre d'époques pour s'entraîner. Les valeurs par défaut sont utilisées si vous ne spécifiez pas d'hyperparamètres d'apprentissage :
+
+ ```py
+ >>> from transformers import TrainingArguments
+
+ >>> training_args = TrainingArguments(
+ ... output_dir="path/to/save/folder/",
+ ... learning_rate=2e-5,
+ ... per_device_train_batch_size=8,
+ ... per_device_eval_batch_size=8,
+ ... num_train_epochs=2,
+ ... )
+ ```
+
+3. Une classe de prétraitement comme un tokenizer, un processeur d'images ou un extracteur de caractéristiques :
+
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+4. Chargez un jeu de données :
+
+ ```py
+ >>> from datasets import load_dataset
+
+ >>> dataset = load_dataset("rotten_tomatoes") # doctest: +IGNORE_RESULT
+ ```
+
+5. Créez une fonction qui transforme le texte du jeu de données en token :
+
+ ```py
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"])
+ ```
+
+ Puis appliquez-la à l'intégralité du jeu de données avec [`~datasets.Dataset.map`]:
+
+ ```py
+ >>> dataset = dataset.map(tokenize_dataset, batched=True)
+ ```
+
+6. Un [`DataCollatorWithPadding`] pour créer un échantillon d'exemples à partir de votre jeu de données :
+
+ ```py
+ >>> from transformers import DataCollatorWithPadding
+
+ >>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+ ```
+
+Maintenant, rassemblez tous ces éléments dans un [`Trainer`] :
+
+```py
+>>> from transformers import Trainer
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=dataset["train"],
+... eval_dataset=dataset["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... ) # doctest: +SKIP
+```
+
+Une fois que vous êtes prêt, appelez la fonction [`~Trainer.train`] pour commencer l'entraînement :
+
+```py
+>>> trainer.train() # doctest: +SKIP
+```
+
+
+
+Pour les tâches - comme la traduction ou la génération de résumé - qui utilisent un modèle séquence à séquence, utilisez plutôt les classes [`Seq2SeqTrainer`] et [`Seq2SeqTrainingArguments`].
+
+
+
+Vous pouvez personnaliser le comportement de la boucle d'apprentissage en redéfinissant les méthodes à l'intérieur de [`Trainer`]. Cela vous permet de personnaliser des caractéristiques telles que la fonction de perte, l'optimiseur et le planificateur. Consultez la documentation de [`Trainer`] pour savoir quelles méthodes peuvent être redéfinies.
+
+L'autre moyen de personnaliser la boucle d'apprentissage est d'utiliser les [Callbacks](./main_classes/callback). Vous pouvez utiliser les callbacks pour intégrer d'autres bibliothèques et inspecter la boucle d'apprentissage afin de suivre la progression ou d'arrêter l'apprentissage plus tôt. Les callbacks ne modifient rien dans la boucle d'apprentissage elle-même. Pour personnaliser quelque chose comme la fonction de perte, vous devez redéfinir le [`Trainer`] à la place.
+
+## Entraînement avec TensorFlow
+
+Tous les modèles sont des modèles standard [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) afin qu'ils puissent être entraînés avec TensorFlow avec l'API [Keras](https://keras.io/). 🤗 Transformers fournit la fonction [`~TFPreTrainedModel.prepare_tf_dataset`] pour charger facilement votre jeu de données comme un `tf.data.Dataset` afin que vous puissiez commencer l'entraînement immédiatement avec les fonctions [`compile`](https://keras.io/api/models/model_training_apis/#compile-method) et [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) de Keras.
+
+1. Vous commencez avec un modèle [`TFPreTrainedModel`] ou [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) :
+
+ ```py
+ >>> from transformers import TFAutoModelForSequenceClassification
+
+ >>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. Une classe de prétraitement comme un tokenizer, un processeur d'images ou un extracteur de caractéristiques :
+
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+3. Créez une fonction qui transforme le texte du jeu de données en token :
+
+ ```py
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"]) # doctest: +SKIP
+ ```
+
+4. Appliquez le tokenizer à l'ensemble du jeu de données avec [`~datasets.Dataset.map`] et passez ensuite le jeu de données et le tokenizer à [`~TFPreTrainedModel.prepare_tf_dataset`]. Vous pouvez également modifier la taille de l'échantillon et mélanger le jeu de données ici si vous le souhaitez :
+
+ ```py
+ >>> dataset = dataset.map(tokenize_dataset) # doctest: +SKIP
+ >>> tf_dataset = model.prepare_tf_dataset(
+ ... dataset, batch_size=16, shuffle=True, tokenizer=tokenizer
+ ... ) # doctest: +SKIP
+ ```
+
+5. Une fois que vous êtes prêt, appelez les fonctions `compile` et `fit` pour commencer l'entraînement :
+
+ ```py
+ >>> from tensorflow.keras.optimizers import Adam
+
+ >>> model.compile(optimizer=Adam(3e-5))
+ >>> model.fit(dataset) # doctest: +SKIP
+ ```
+
+## Et après ?
+
+Maintenant que vous avez terminé la visite rapide de 🤗 Transformers, consultez nos guides et apprenez à faire des choses plus spécifiques comme créer un modèle personnalisé, finetuner un modèle pour une tâche, et comment entraîner un modèle avec un script. Si vous souhaitez en savoir plus sur les concepts fondamentaux de 🤗 Transformers, jetez un œil à nos guides conceptuels !
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/run_scripts_fr.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/run_scripts_fr.md
new file mode 100644
index 0000000000000000000000000000000000000000..0344ff2cec3d2d4f964dbacfc27344aa90e56447
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/run_scripts_fr.md
@@ -0,0 +1,355 @@
+
+
+# Entraîner avec un script
+
+En plus des [notebooks](./notebooks) de 🤗 Transformers, il existe également des exemples de scripts démontrant comment entraîner un modèle pour une tâche avec [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch), [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow) ou [JAX/Flax](https://github.com/huggingface/transformers/tree/main/examples/flax).
+
+
+Vous trouverez également des scripts que nous avons utilisé dans nos [projets de recherche](https://github.com/huggingface/transformers/tree/main/examples/research_projects) et des [exemples "legacy"](https://github.com/huggingface/transformers/tree/main/examples/legacy) qui sont des contributions de la communauté. Ces scripts ne sont pas activement maintenus et nécessitent une version spécifique de 🤗 Transformers qui sera probablement incompatible avec la dernière version de la librairie.
+
+Les exemples de scripts ne sont pas censés fonctionner immédiatement pour chaque problème, et il se peut que vous ayez besoin d'adapter le script au problème que vous essayez de résoudre. Pour vous aider dans cette tâche, la plupart des scripts exposent entièrement la manière dont les données sont prétraitées, vous permettant de les modifier selon vos besoins.
+
+Pour toute fonctionnalité que vous souhaitez implémenter dans un script d'exemple, veuillez en discuter sur le [forum](https://discuss.huggingface.co/) ou dans une [issue](https://github.com/huggingface/transformers/issues) avant de soumettre une Pull Request. Bien que nous acceptions les corrections de bugs, il est peu probable que nous fusionnions une Pull Request (opération "merge" dans Git) ajoutant plus de fonctionnalités au détriment de la lisibilité.
+
+Ce guide vous montrera comment exécuter un script d'entraînement de résumé en exemple avec [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization) et [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/summarization). Tous les exemples sont censés fonctionner avec les deux frameworks, sauf indication contraire.
+
+## Configuration
+
+Pour exécuter avec succès la dernière version des scripts d'exemple, vous devez **installer 🤗 Transformers à partir du code source** dans un nouvel environnement virtuel :
+
+```bash
+git clone https://github.com/huggingface/transformers
+cd transformers
+pip install .
+```
+
+Pour les versions plus anciennes des exemples de scripts, cliquez sur le bouton ci-dessous :
+
+
+ Exemples pour les anciennes versions de Transformers 🤗
+
+
+
+Ensuite, changez votre clone actuel de 🤗 Transformers pour une version spécifique, comme par exemple v3.5.1 :
+
+```bash
+git checkout tags/v3.5.1
+```
+
+Après avoir configuré la bonne version de la librairie, accédez au dossier d'exemple de votre choix et installez les prérequis spécifiques à l'exemple.
+
+```bash
+pip install -r requirements.txt
+```
+
+## Exécuter un script
+
+
+
+
+Le script d'exemple télécharge et prétraite un jeu de données à partir de la bibliothèque 🤗 [Datasets](https://huggingface.co/docs/datasets/). Ensuite, le script affine un ensemble de données à l'aide de [Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) sur une architecture qui prend en charge la tâche de résumé. L'exemple suivant montre comment ajuster le modèle [T5-small](https://huggingface.co/google-t5/t5-small) sur les données [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail). Le modèle T5 nécessite un argument supplémentaire `source_prefix` en raison de la façon dont il a été entraîné. Cette invite permet à T5 de savoir qu'il s'agit d'une tâche de résumé.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+
+Le script d'exemple télécharge et prétraite un jeu de données à partir de la bibliothèque 🤗 [Datasets](https://huggingface.co/docs/datasets/). Ensuite, le script ajuste un modèle à l'aide de Keras sur une architecture qui prend en charge la tâche de résumé. L'exemple suivant montre comment ajuster le modèle [T5-small](https://huggingface.co/google-t5/t5-small) sur le jeu de données [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail). Le modèle T5 nécessite un argument supplémentaire source_prefix en raison de la façon dont il a été entraîné. Cette invite permet à T5 de savoir qu'il s'agit d'une tâche de résumé.
+
+```bash
+python examples/tensorflow/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## Entraînement distribué et précision mixte
+
+[Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) prend en charge l'entraînement distribué et la précision mixte, ce qui signifie que vous pouvez également les utiliser dans un script. Pour activer ces deux fonctionnalités :
+
+- Ajoutez l'argument fp16 pour activer la précision mixte.
+- Définissez le nombre de GPU à utiliser avec l'argument `nproc_per_node`.
+
+```bash
+torchrun \
+ --nproc_per_node 8 pytorch/summarization/run_summarization.py \
+ --fp16 \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+Les scripts TensorFlow utilisent une Strategie en Miroir [`MirroredStrategy`](https://www.tensorflow.org/guide/distributed_training#mirroredstrategy) pour l'entraînement distribué, et vous n'avez pas besoin d'ajouter d'arguments supplémentaires au script d'entraînement. Le script TensorFlow utilisera plusieurs GPU par défaut s'ils sont disponibles.
+
+## Exécuter un script sur un TPU
+
+
+
+
+Les unités de traitement de tenseurs (UTT) (TPU) sont spécialement conçues pour accélérer les performances. PyTorch prend en charge les TPU avec le compilateur de deep learning [XLA](https://www.tensorflow.org/xla). Pour utiliser un TPU, lancez le script xla_spawn.py et utilisez l'argument num_cores pour définir le nombre de cœurs TPU que vous souhaitez utilise
+
+```bash
+python xla_spawn.py --num_cores 8 \
+ summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+Les scripts TensorFlow utilisent une [`TPUStrategy`](https://www.tensorflow.org/guide/distributed_training#tpustrategy) pour l'entraînement sur TPU. Pour utiliser un TPU, passez le nom de la ressource TPU à l'argument tpu.
+
+```bash
+python run_summarization.py \
+ --tpu name_of_tpu_resource \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## Exécuter un script avec 🤗 Accelerate
+
+🤗 [Accelerate](https://huggingface.co/docs/accelerate) est une bibliothèque uniquement pour PyTorch qui offre une méthode unifiée pour entraîner un modèle sur plusieurs types de configurations (CPU uniquement, plusieurs GPU, TPU) tout en maintenant une visibilité complète sur la boucle d'entraînement PyTorch. Assurez-vous que vous avez installé 🤗 Accelerate si ce n'est pas déjà le cas.
+
+> Note : Comme Accelerate est en développement rapide, la version git d'accelerate doit être installée pour exécuter les scripts.
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+Au lieu du script `run_summarization.py`, vous devez utiliser le script `run_summarization_no_trainer.py`. Les scripts compatibles avec 🤗 Accelerate auront un fichier `task_no_trainer.py` dans le dossier. Commencez par exécuter la commande suivante pour créer et enregistrer un fichier de configuration.
+
+```bash
+accelerate config
+```
+
+Testez votre configuration pour vous assurer qu'elle est correctement configurée :
+
+```bash
+accelerate test
+```
+
+Maintenant, vous êtes prêt à lancer l'entraînement :
+
+```bash
+accelerate launch run_summarization_no_trainer.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir ~/tmp/tst-summarization
+```
+
+## Utiliser un jeu de données personnalisé
+
+Le script de résumé prend en charge les jeux de données personnalisés tant qu'ils sont au format CSV ou JSON Line. Lorsque vous utilisez votre propre jeu de données, vous devez spécifier plusieurs arguments supplémentaires :
+
+- `train_file` et `validation_file` spécifient le chemin vers vos fichiers d'entraînement et de validation.
+- `text_column` est le texte d'entrée à résumer.
+- `summary_column` est le texte cible à produire.
+
+Un exemple de script de résumé utilisant un ensemble de données personnalisé ressemblerait à ceci :
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --train_file path_to_csv_or_jsonlines_file \
+ --validation_file path_to_csv_or_jsonlines_file \
+ --text_column text_column_name \
+ --summary_column summary_column_name \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --overwrite_output_dir \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --predict_with_generate
+```
+
+## Tester un script
+Il est souvent judicieux d'exécuter votre script sur un plus petit nombre d'exemples de jeu de données pour s'assurer que tout fonctionne comme prévu avant de s'engager sur un jeu de données complet qui pourrait prendre des heures à traiter. Utilisez les arguments suivants pour tronquer le jeu de données à un nombre maximal d'échantillons :
+
+- `max_train_samples`
+- `max_eval_samples`
+- `max_predict_samples`
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --max_train_samples 50 \
+ --max_eval_samples 50 \
+ --max_predict_samples 50 \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+Tous les scripts d'exemple ne prennent pas en charge l'argument `max_predict_samples`. Si vous n'êtes pas sûr que votre script prenne en charge cet argument, ajoutez l'argument `-h` pour vérifier.
+
+```bash
+examples/pytorch/summarization/run_summarization.py -h
+```
+
+## Reprendre l'entraînement à partir d'un point de contrôle
+
+Une autre option utile est de reprendre l'entraînement à partir d'un point de contrôle précédent. Cela vous permettra de reprendre là où vous vous étiez arrêté sans recommencer si votre entraînement est interrompu. Il existe deux méthodes pour reprendre l'entraînement à partir d'un point de contrôle.
+
+La première méthode utilise l'argument `output_dir previous_output_dir` pour reprendre l'entraînement à partir du dernier point de contrôle stocké dans `output_dir`. Dans ce cas, vous devez supprimer l'argument `overwrite_output_dir`.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --output_dir previous_output_dir \
+ --predict_with_generate
+```
+
+La seconde méthode utilise l'argument `resume_from_checkpoint path_to_specific_checkpoint` pour reprendre l'entraînement à partir d'un dossier de point de contrôle spécifique.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --resume_from_checkpoint path_to_specific_checkpoint \
+ --predict_with_generate
+```
+
+## Partage ton modèle
+
+Tous les scripts peuvent télécharger votre modèle final sur le Model Hub. Assurez-vous que vous êtes connecté à Hugging Face avant de commencer :
+
+```bash
+huggingface-cli login
+```
+
+Ensuite, ajoutez l'argument `push_to_hub` au script. Cet argument créera un dépôt avec votre nom d'utilisateur Hugging Face et le nom du dossier spécifié dans `output_dir`.
+
+
+Pour donner un nom spécifique à votre dépôt, utilisez l'argument `push_to_hub_model_id` pour l'ajouter. Le dépôt sera automatiquement listé sous votre namespace.
+
+L'exemple suivant montre comment télécharger un modèle avec un nom de dépôt spécifique :
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --push_to_hub \
+ --push_to_hub_model_id finetuned-t5-cnn_dailymail \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/task_summary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/task_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..f730264f95e86fe8bb44cbb338f72e48af607125
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/task_summary.md
@@ -0,0 +1,341 @@
+
+
+# Ce que 🤗 Transformers peut faire
+
+🤗 Transformers est une bibliothèque de modèles préentraînés à la pointe de la technologie pour les tâches de traitement du langage naturel (NLP), de vision par ordinateur et de traitement audio et de la parole. Non seulement la bibliothèque contient des modèles Transformer, mais elle inclut également des modèles non-Transformer comme des réseaux convolutionnels modernes pour les tâches de vision par ordinateur. Si vous regardez certains des produits grand public les plus populaires aujourd'hui, comme les smartphones, les applications et les téléviseurs, il est probable qu'une technologie d'apprentissage profond soit derrière. Vous souhaitez supprimer un objet de fond d'une photo prise avec votre smartphone ? C'est un exemple de tâche de segmentation panoptique (ne vous inquiétez pas si vous ne savez pas encore ce que cela signifie, nous le décrirons dans les sections suivantes !).
+
+Cette page fournit un aperçu des différentes tâches de traitement de la parole et de l'audio, de vision par ordinateur et de NLP qui peuvent être résolues avec la bibliothèque 🤗 Transformers en seulement trois lignes de code !
+
+## Audio
+
+Les tâches de traitement audio et de la parole sont légèrement différentes des autres modalités principalement parce que l'audio en tant que donnée d'entrée est un signal continu. Contrairement au texte, un signal audio brut ne peut pas discrétisé de la manière dont une phrase peut être divisée en mots. Pour contourner cela, le signal audio brut est généralement échantillonné à intervalles réguliers. Si vous prenez plus d'échantillons dans un intervalle, le taux d'échantillonnage est plus élevé et l'audio ressemble davantage à la source audio originale.
+
+Les approches précédentes prétraitaient l'audio pour en extraire des caractéristiques utiles. Il est maintenant plus courant de commencer les tâches de traitement audio et de la parole en donnant directement le signal audio brut à un encodeur de caractéristiques (*feature encoder* en anglais) pour extraire une représentation de l'audio. Cela correspond à l'étape de prétraitement et permet au modèle d'apprendre les caractéristiques les plus essentielles du signal.
+
+### Classification audio
+
+La classification audio est une tâche qui consiste à attribuer une classe, parmi un ensemble de classes prédéfini, à un audio. La classification audio englobe de nombreuses applications spécifiques, dont certaines incluent :
+
+* la classification d'environnements sonores : attribuer une classe (catégorie) à l'audio pour indiquer l'environnement associé, tel que "bureau", "plage" ou "stade".
+* la détection d'événements sonores : étiqueter l'audio avec une étiquette d'événement sonore ("klaxon de voiture", "appel de baleine", "verre brisé")
+* l'identification d'éléments sonores : attribuer des tags (*étiquettes* en français) à l'audio pour marquer des sons spécifiques, comme "chant des oiseaux" ou "identification du locuteur lors d'une réunion".
+* la classification musicale : attribuer un genre à la musique, comme "metal", "hip-hop" ou "country".
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="audio-classification", model="superb/hubert-base-superb-er")
+>>> preds = classifier("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4532, 'label': 'hap'},
+ {'score': 0.3622, 'label': 'sad'},
+ {'score': 0.0943, 'label': 'neu'},
+ {'score': 0.0903, 'label': 'ang'}]
+```
+
+### Reconnaissance vocale
+
+La reconnaissance vocale (*Automatic Speech Recognition* ou ASR en anglais) transcrit la parole en texte. C'est l'une des tâches audio les plus courantes en partie parce que la parole est une forme de communication la plus naturelle pour nous, humains. Aujourd'hui, les systèmes ASR sont intégrés dans des produits technologiques "intelligents" comme les enceintes, les téléphones et les voitures. Il est désormais possible de demander à nos assistants virtuels de jouer de la musique, de définir des rappels et de nous indiquer la météo.
+
+Mais l'un des principaux défis auxquels les architectures Transformer contribuent à résoudre est celui des langues à faibles ressources, c'est-à-dire des langues pour lesquelles il existe peu de données étiquetées. En préentraînant sur de grandes quantités de données vocales d'un autre language plus ou moins similaire, le réglage fin (*fine-tuning* en anglais) du modèle avec seulement une heure de données vocales étiquetées dans une langue à faibles ressources peut tout de même produire des résultats de haute qualité comparés aux systèmes ASR précédents entraînés sur 100 fois plus de données étiquetées.
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline(task="automatic-speech-recognition", model="openai/whisper-small")
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+## Vision par ordinateur
+
+L'une des premières réussites en vision par ordinateur a été la reconnaissance des numéros de code postal à l'aide d'un [réseau de neurones convolutionnel (CNN)](glossary#convolution). Une image est composée de pixels, chacun ayant une valeur numérique, ce qui permet de représenter facilement une image sous forme de matrice de valeurs de pixels. Chaque combinaison de valeurs de pixels correspond aux couleurs d'une image.
+
+Il existe deux approches principales pour résoudre les tâches de vision par ordinateur :
+
+1. Utiliser des convolutions pour apprendre les caractéristiques hiérarchiques d'une image, des détails de bas niveau aux éléments abstraits de plus haut niveau.
+2. Diviser l'image en morceaux (*patches* en anglais) et utiliser un Transformer pour apprendre progressivement comment chaque morceau est lié aux autres pour former l'image complète. Contrairement à l'approche ascendante des CNNs, cette méthode ressemble à un processus où l'on démarre avec une image floue pour ensuite la mettre au point petit à petit.
+
+### Classification d'images
+
+La classification d'images consiste à attribuer une classe, parmi un ensemble de classes prédéfini, à toute une image. Comme pour la plupart des tâches de classification, les cas d'utilisation pratiques sont nombreux, notamment :
+
+- Santé : classification d'images médicales pour détecter des maladies ou surveiller l'état de santé des patients.
+- Environnement : classification d'images satellites pour suivre la déforestation, aider à la gestion des terres ou détecter les incendies de forêt.
+- Agriculture : classification d'images de cultures pour surveiller la santé des plantes ou des images satellites pour analyser l'utilisation des terres.
+- Écologie : classification d'images d'espèces animales ou végétales pour suivre les populations fauniques ou les espèces menacées.
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="image-classification")
+>>> preds = classifier(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> print(*preds, sep="\n")
+{'score': 0.4335, 'label': 'lynx, catamount'}
+{'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}
+{'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}
+{'score': 0.0239, 'label': 'Egyptian cat'}
+{'score': 0.0229, 'label': 'tiger cat'}
+```
+
+### Détection d'objets
+
+La détection d'objets, à la différence de la classification d'images, identifie plusieurs objets dans une image ainsi que leurs positions, généralement définies par des boîtes englobantes (*bounding boxes* en anglais). Voici quelques exemples d'applications :
+
+- Véhicules autonomes : détection des objets de la circulation, tels que les véhicules, piétons et feux de signalisation.
+- Télédétection : surveillance des catastrophes, planification urbaine et prévisions météorologiques.
+- Détection de défauts : identification des fissures ou dommages structurels dans les bâtiments, ainsi que des défauts de fabrication.
+
+```py
+>>> from transformers import pipeline
+
+>>> detector = pipeline(task="object-detection")
+>>> preds = detector(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"], "box": pred["box"]} for pred in preds]
+>>> preds
+[{'score': 0.9865,
+ 'label': 'cat',
+ 'box': {'xmin': 178, 'ymin': 154, 'xmax': 882, 'ymax': 598}}]
+```
+
+### Segmentation d'images
+
+La segmentation d'images est une tâche qui consiste à attribuer une classe à chaque pixel d'une image, ce qui la rend plus précise que la détection d'objets, qui se limite aux boîtes englobantes (*bounding boxes* en anglais). Elle permet ainsi de détecter les objets à la précision du pixel. Il existe plusieurs types de segmentation d'images :
+
+- Segmentation d'instances : en plus de classifier un objet, elle identifie chaque instance distincte d'un même objet (par exemple, "chien-1", "chien-2").
+- Segmentation panoptique : combine segmentation sémantique et segmentation d'instances, attribuant à chaque pixel une classe sémantique **et** une instance spécifique.
+
+Ces techniques sont utiles pour les véhicules autonomes, qui doivent cartographier leur environnement pixel par pixel pour naviguer en toute sécurité autour des piétons et des véhicules. Elles sont également précieuses en imagerie médicale, où la précision au niveau des pixels permet de détecter des anomalies cellulaires ou des caractéristiques d'organes. Dans le commerce en ligne, la segmentation est utilisée pour des essayages virtuels de vêtements ou des expériences de réalité augmentée, en superposant des objets virtuels sur des images du monde réel via la caméra.
+
+```py
+>>> from transformers import pipeline
+
+>>> segmenter = pipeline(task="image-segmentation")
+>>> preds = segmenter(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> print(*preds, sep="\n")
+{'score': 0.9879, 'label': 'LABEL_184'}
+{'score': 0.9973, 'label': 'snow'}
+{'score': 0.9972, 'label': 'cat'}
+```
+
+### Estimation de la profondeur
+
+L'estimation de la profondeur consiste à prédire la distance de chaque pixel d'une image par rapport à la caméra. Cette tâche est cruciale pour comprendre et reconstruire des scènes réelles. Par exemple, pour les voitures autonomes, il est essentiel de déterminer la distance des objets tels que les piétons, les panneaux de signalisation et les autres véhicules pour éviter les collisions. L'estimation de la profondeur permet également de créer des modèles 3D à partir d'images 2D, ce qui est utile pour générer des représentations détaillées de structures biologiques ou de bâtiments.
+
+Il existe deux principales approches pour estimer la profondeur :
+
+- Stéréo : la profondeur est estimée en comparant deux images d'une même scène prises sous des angles légèrement différents.
+- Monoculaire : la profondeur est estimée à partir d'une seule image.
+
+```py
+>>> from transformers import pipeline
+
+>>> depth_estimator = pipeline(task="depth-estimation")
+>>> preds = depth_estimator(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+```
+
+## Traitement du langage naturel
+
+Les tâches de traitement du langage naturel (*Natural Language Processing* ou *NLP* en anglais) sont courantes car le texte est une forme naturelle de communication pour nous. Pour qu'un modèle puisse traiter le texte, celui-ci doit être *tokenisé*, c'est-à-dire divisé en mots ou sous-mots appelés "*tokens*", puis converti en nombres. Ainsi, une séquence de texte peut être représentée comme une séquence de nombres, qui peut ensuite être utilisée comme données d'entrée pour un modèle afin de résoudre diverses tâches de traitement du langage naturel.
+
+### Classification de texte
+
+La classification de texte attribue une classe à une séquence de texte (au niveau d'une phrase, d'un paragraphe ou d'un document) à partir d'un ensemble de classes prédéfini. Voici quelques applications pratiques :
+
+- **Analyse des sentiments** : étiqueter le texte avec une polarité telle que `positive` ou `négative`, ce qui aide à la prise de décision dans des domaines comme la politique, la finance et le marketing.
+- **Classification de contenu** : organiser et filtrer les informations en attribuant des *tags* sur des sujets spécifiques, comme `météo`, `sports` ou `finance`, dans les flux d'actualités et les réseaux sociaux.
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="sentiment-analysis")
+>>> preds = classifier("Hugging Face is the best thing since sliced bread!")
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.9991, 'label': 'POSITIVE'}]
+```
+
+### Classification des tokens
+
+Dans les tâches de traitement du language naturel, le texte est d'abord prétraité en le séparant en mots ou sous-mots individuels, appelés *[tokens](glossary#token)*. La classification des tokens attribue une classe à chaque token à partir d'un ensemble de classes prédéfini.
+
+Voici deux types courants de classification des tokens :
+
+- **Reconnaissance d'entités nommées (*Named Entity Recognition* ou *NER* en anglais)** : étiqueter un token selon une catégorie d'entité, telle qu'organisation, personne, lieu ou date. La NER est particulièrement utilisée dans les contextes biomédicaux pour identifier des gènes, des protéines et des noms de médicaments.
+- **Étiquetage des parties du discours (*Part of Speech* ou *POS* en anglais)** : étiqueter un token en fonction de sa partie du discours, comme nom, verbe ou adjectif. Le POS est utile pour les systèmes de traduction afin de comprendre comment deux mots identiques peuvent avoir des rôles grammaticaux différents (par exemple, "banque" comme nom versus "banque" comme verbe).
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="ner")
+>>> preds = classifier("Hugging Face is a French company based in New York City.")
+>>> preds = [
+... {
+... "entity": pred["entity"],
+... "score": round(pred["score"], 4),
+... "index": pred["index"],
+... "word": pred["word"],
+... "start": pred["start"],
+... "end": pred["end"],
+... }
+... for pred in preds
+... ]
+>>> print(*preds, sep="\n")
+{'entity': 'I-ORG', 'score': 0.9968, 'index': 1, 'word': 'Hu', 'start': 0, 'end': 2}
+{'entity': 'I-ORG', 'score': 0.9293, 'index': 2, 'word': '##gging', 'start': 2, 'end': 7}
+{'entity': 'I-ORG', 'score': 0.9763, 'index': 3, 'word': 'Face', 'start': 8, 'end': 12}
+{'entity': 'I-MISC', 'score': 0.9983, 'index': 6, 'word': 'French', 'start': 18, 'end': 24}
+{'entity': 'I-LOC', 'score': 0.999, 'index': 10, 'word': 'New', 'start': 42, 'end': 45}
+{'entity': 'I-LOC', 'score': 0.9987, 'index': 11, 'word': 'York', 'start': 46, 'end': 50}
+{'entity': 'I-LOC', 'score': 0.9992, 'index': 12, 'word': 'City', 'start': 51, 'end': 55}
+```
+
+### Réponse à des questions - (*Question Answering*)
+
+La réponse à des questions (*Question Answering* ou *QA* en anglais) est une tâche de traitement du language naturel qui consiste à fournir une réponse à une question, parfois avec l'aide d'un contexte (domaine ouvert) et d'autres fois sans contexte (domaine fermé). Cette tâche intervient lorsqu'on interroge un assistant virtuel, par exemple pour savoir si un restaurant est ouvert. Elle est également utilisée pour le support client, technique, et pour aider les moteurs de recherche à fournir des informations pertinentes.
+
+Il existe deux types courants de réponse à des questions :
+
+- **Extractive** : pour une question donnée et un contexte fourni, la réponse est extraite directement du texte du contexte par le modèle.
+- **Abstractive** : pour une question donnée et un contexte, la réponse est générée à partir du contexte. Cette approche utilise le [`Text2TextGenerationPipeline`] plutôt que le [`QuestionAnsweringPipeline`] montré ci-dessous.
+
+
+```py
+>>> from transformers import pipeline
+
+>>> question_answerer = pipeline(task="question-answering")
+>>> preds = question_answerer(
+... question="What is the name of the repository?",
+... context="The name of the repository is huggingface/transformers",
+... )
+>>> print(
+... f"score: {round(preds['score'], 4)}, start: {preds['start']}, end: {preds['end']}, answer: {preds['answer']}"
+... )
+score: 0.9327, start: 30, end: 54, answer: huggingface/transformers
+```
+
+### Résumé de texte - (*Summarization*)
+
+Le résumé de text consiste à créer une version plus courte d'un texte tout en conservant l'essentiel du sens du document original. C'est une tâche de séquence à séquence qui produit un texte plus condensé à partir du texte initial. Cette technique est utile pour aider les lecteurs à saisir rapidement les points clés de longs documents, comme les projets de loi, les documents juridiques et financiers, les brevets, et les articles scientifiques.
+
+Il existe deux types courants de summarization :
+
+- **Extractive** : identifier et extraire les phrases les plus importantes du texte original.
+- **Abstractive** : générer un résumé qui peut inclure des mots nouveaux non présents dans le texte d'origine. Le [`SummarizationPipeline`] utilise l'approche abstractive.
+
+```py
+>>> from transformers import pipeline
+
+>>> summarizer = pipeline(task="summarization")
+>>> summarizer(
+... "In this work, we presented the Transformer, the first sequence transduction model based entirely on attention, replacing the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention. For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers. On both WMT 2014 English-to-German and WMT 2014 English-to-French translation tasks, we achieve a new state of the art. In the former task our best model outperforms even all previously reported ensembles."
+... )
+[{'summary_text': ' The Transformer is the first sequence transduction model based entirely on attention . It replaces the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention . For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers .'}]
+```
+
+### Traduction
+
+La traduction convertit un texte d'une langue à une autre. Elle facilite la communication entre personnes de différentes langues, permet de toucher des audiences plus larges et peut aussi servir d'outil d'apprentissage pour ceux qui apprennent une nouvelle langue. Comme le résumé de texte, la traduction est une tâche de séquence à séquence, où le modèle reçoit une séquence d'entrée (un texte est ici vu comme une séquence de mots, ou plus précisément de tokens) et produit une séquence de sortie dans la langue cible.
+
+Initialement, les modèles de traduction étaient principalement monolingues, mais il y a eu récemment un intérêt croissant pour les modèles multilingues capables de traduire entre plusieurs paires de langues.
+
+```py
+>>> from transformers import pipeline
+
+>>> text = "translate English to French: Hugging Face is a community-based open-source platform for machine learning."
+>>> translator = pipeline(task="translation", model="google-t5/t5-small")
+>>> translator(text)
+[{'translation_text': "Hugging Face est une tribune communautaire de l'apprentissage des machines."}]
+```
+
+### Modélisation du langage
+
+La modélisation du langage consiste à prédire un mot dans un texte. Cette tâche est devenue très populaire en traitement du language naturel, car un modèle de langage préentraîné sur cette tâche peut ensuite être ajusté (*finetuned*) pour accomplir de nombreuses autres tâches. Récemment, les grands modèles de langage (LLMs) ont suscité beaucoup d'intérêt pour leur capacité à apprendre avec peu ou pas de données spécifiques à une tâche, ce qui leur permet de résoudre des problèmes pour lesquels ils n'ont pas été explicitement entraînés. Ces modèles peuvent générer du texte fluide et convaincant, bien qu'il soit important de vérifier leur précision.
+
+Il existe deux types de modélisation du langage :
+
+- **Causale** : le modèle prédit le token suivant dans une séquence, avec les tokens futurs masqués.
+
+ ```py
+ >>> from transformers import pipeline
+
+ >>> prompt = "Hugging Face is a community-based open-source platform for machine learning."
+ >>> generator = pipeline(task="text-generation")
+ >>> generator(prompt) # doctest: +SKIP
+ ```
+
+- **Masquée** : le modèle prédit un token masqué dans une séquence en ayant accès à tous les autres tokens de la séquence (passé et futur).
+
+ ```py
+ >>> text = "Hugging Face is a community-based open-source for machine learning."
+ >>> fill_mask = pipeline(task="fill-mask")
+ >>> preds = fill_mask(text, top_k=1)
+ >>> preds = [
+ ... {
+ ... "score": round(pred["score"], 4),
+ ... "token": pred["token"],
+ ... "token_str": pred["token_str"],
+ ... "sequence": pred["sequence"],
+ ... }
+ ... for pred in preds
+ ... ]
+ >>> preds
+ [{'score': 0.2236,
+ 'token': 1761,
+ 'token_str': ' platform',
+ 'sequence': 'Hugging Face is a community-based open-source platform for machine learning.'}]
+ ```
+
+## Multimodal
+
+Les tâches multimodales nécessitent qu'un modèle traite plusieurs types de données (texte, image, audio, vidéo) pour résoudre un problème spécifique. Par exemple, la génération de légendes pour les images est une tâche multimodale où le modèle prend une image en entrée et produit une séquence de texte décrivant l'image ou ses propriétés.
+
+Bien que les modèles multimodaux traitent divers types de données, ils convertissent toutes ces données en *embeddings* (vecteurs ou listes de nombres contenant des informations significatives). Pour des tâches comme la génération de légendes pour les images, le modèle apprend les relations entre les *embeddings* d'images et ceux de texte.
+
+### Réponse à des questions sur des documents - (*Document Question Answering*)
+
+La réponse à des questions sur des documents consiste à répondre à des questions en langage naturel en utilisant un document comme référence. Contrairement à la réponse à des questions au niveau des tokens, qui prend du texte en entrée, cette tâche prend une image d'un document ainsi qu'une question concernant ce document, et fournit une réponse. Elle est utile pour analyser des données structurées et extraire des informations clées. Par exemple, à partir d'un reçu, on peut extraire des informations telles que le montant total et le change dû.
+
+```py
+>>> from transformers import pipeline
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "https://huggingface.co/datasets/hf-internal-testing/example-documents/resolve/main/jpeg_images/2.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> doc_question_answerer = pipeline("document-question-answering", model="magorshunov/layoutlm-invoices")
+>>> preds = doc_question_answerer(
+... question="What is the total amount?",
+... image=image,
+... )
+>>> preds
+[{'score': 0.8531, 'answer': '17,000', 'start': 4, 'end': 4}]
+```
+
+En espérant que cette page vous ait donné plus d'informations sur les différents types de tâches dans chaque modalité et l'importance pratique de chacune d'elles. Dans la [section suivante](tasks_explained), vous découvrirez **comment** 🤗 Transformers fonctionne pour résoudre ces tâches.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/tasks_explained.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/tasks_explained.md
new file mode 100644
index 0000000000000000000000000000000000000000..a39096b2b86258ac4aaf03086385f70ba7d68d2a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/tasks_explained.md
@@ -0,0 +1,294 @@
+
+
+# Comment 🤗 Transformers résout ces tâches
+
+Dans [Ce que 🤗 Transformers peut faire](task_summary), vous avez découvert les tâches de traitement du langage naturel (NLP), de traitement de la parole et de l'audio, de vision par ordinateur, ainsi que certaines de leurs applications importantes. Cette page se penche sur la manière dont les modèles résolvent ces tâches et explique les processus en arrière-plan. Bien que différents modèles puissent utiliser diverses techniques ou approches innovantes, les modèles Transformer suivent généralement une idée commune. Grâce à leur architecture flexible, la plupart des modèles sont basés sur un encodeur, un décodeur ou une combinaison encodeur-décodeur. En plus des modèles Transformer, notre bibliothèque comprend également des réseaux de neurones convolutifs (CNN), qui restent utilisés pour les tâches de vision par ordinateur. Nous expliquerons aussi le fonctionnement d'un CNN moderne.
+
+Voici comment différents modèles résolvent des tâches spécifiques :
+
+- [Wav2Vec2](model_doc/wav2vec2) pour la classification audio et la reconnaissance vocale (*ASR* en anglais)
+- [Vision Transformer (ViT)](model_doc/vit) et [ConvNeXT](model_doc/convnext) pour la classification d'images
+- [DETR](model_doc/detr) pour la détection d'objets
+- [Mask2Former](model_doc/mask2former) pour la segmentation d'images
+- [GLPN](model_doc/glpn) pour l'estimation de la profondeur
+- [BERT](model_doc/bert) pour les tâches de traitement du language naturel telles que la classification de texte, la classification des tokens et la réponse à des questions utilisant un encodeur
+- [GPT2](model_doc/gpt2) pour les tâches de traitement du language naturel telles que la génération de texte utilisant un décodeur
+- [BART](model_doc/bart) pour les tâches de traitement du language naturel telles que le résumé de texte et la traduction utilisant un encodeur-décodeur
+
+
+
+Avant de poursuivre, il est utile d'avoir quelques connaissances de base sur l'architecture des Transformers. Comprendre le fonctionnement des encodeurs, des décodeurs et du mécanisme d'attention vous aidera à saisir comment les différents modèles Transformer fonctionnent. Si vous débutez ou avez besoin d'un rappel, consultez notre [cours](https://huggingface.co/course/chapter1/4?fw=pt) pour plus d'informations !
+
+
+
+## Paroles et audio
+
+[Wav2Vec2](model_doc/wav2vec2) est un modèle auto-supervisé qui est préentraîné sur des données de parole non étiquetées et ajusté sur des données étiquetées pour des tâches telles que la classification audio et la reconnaissance vocale (ASR).
+
+
+
+
+
+Une troisième approche combine les Transformers avec des convolutions (par exemple, [Convolutional Vision Transformer](model_doc/cvt) ou [LeViT](model_doc/levit)). Nous ne discuterons pas de ces approches ici, car elles mélangent simplement les deux approches que nous examinons.
+
+
+
+ViT et ConvNeXT sont couramment utilisés pour la classification d'images. Pour d'autres tâches de vision par ordinateur comme la détection d'objets, la segmentation et l'estimation de la profondeur, nous examinerons respectivement DETR, Mask2Former et GLPN, qui sont mieux adaptés à ces tâches.
+
+### Classification d'images
+
+ViT et ConvNeXT peuvent tous deux être utilisés pour la classification d'images ; la principale différence réside dans leurs approches : ViT utilise un mécanisme d'attention tandis que ConvNeXT repose sur des convolutions.
+
+#### Transformer
+
+[ViT](model_doc/vit) remplace entièrement les convolutions par une architecture Transformer pure. Si vous êtes déjà familiarisé avec le Transformer original, vous trouverez que ViT suit des principes similaires, mais adaptés pour traiter les images comme des séquences de patches.
+
+
+
+
+
+Cette section explique brièvement les convolutions, mais il serait utile d'avoir une compréhension préalable de la façon dont elles modifient la forme et la taille d'une image. Si vous n'êtes pas familier avec les convolutions, consultez le [chapitre sur les réseaux de neurones convolutionnels](https://github.com/fastai/fastbook/blob/master/13_convolutions.ipynb) du livre fastai !
+
+
+
+[ConvNeXT](model_doc/convnext) est une architecture CNN qui adopte des conceptions de réseau modernes pour améliorer les performances. Cependant, les convolutions restent au cœur du modèle. D'un point de vue général, une [convolution](glossary#convolution) est une opération où une matrice plus petite (*noyau*) est multipliée par une petite fenêtre de pixels de l'image. Elle calcule certaines caractéristiques à partir de cette fenêtre, comme une texture particulière ou la courbure d'une ligne. Ensuite, elle se déplace vers la fenêtre suivante de pixels ; la distance parcourue par la convolution est appelée le *stride*.
+
+
+
+
Une convolution de base sans padding ni stride, tirée de Un guide des calculs de convolution pour l'apprentissage profond.
+
+Vous pouvez alimenter la sortie d'une couche convolutionnelle à une autre couche convolutionnelle. À chaque couche successive, le réseau apprend des caractéristiques de plus en plus complexes et abstraites, telles que des objets spécifiques comme des hot-dogs ou des fusées. Entre les couches convolutionnelles, il est courant d'ajouter des couches de pooling pour réduire la dimensionnalité et rendre le modèle plus robuste aux variations de position des caractéristiques.
+
+
+
+
+
+
+
+
+
+
+
+💡 Une fois BERT préentraîné, il est incroyablement facile de l’adapter à diverses tâches ! Il vous suffit d’ajouter une tête spécifique au modèle préentraîné pour transformer les états cachés en la sortie souhaitée.
+
+
+
+### Génération de texte
+
+[GPT-2](model_doc/gpt2) est un modèle basé uniquement sur le décodeur, préentraîné sur une grande quantité de texte. Il peut générer du texte convaincant (bien que parfois inexact !) à partir d'une invite et accomplir d'autres tâches de NLP, comme la réponse aux questions, même s'il n'a pas été spécifiquement entraîné pour ces tâches.
+
+
+
+
+
+Pour plus d'informations sur la génération de texte, consultez le guide sur les [stratégies de génération de texte](generation_strategies) !
+
+
+
+### Résumé de texte
+
+Les modèles encodeur-décodeur tels que [BART](model_doc/bart) et [T5](model_doc/t5) sont conçus pour les tâches de résumé en mode séquence-à-séquence. Dans cette section, nous expliquerons le fonctionnement de BART, puis vous aurez l'occasion de découvrir comment réaliser un réglagle fin (*fine-tuning*) de T5.
+
+
+
+
+
+Pour plus d'informations sur la génération de texte, consultez le guide sur les [stratégies de génération de texte](generation_strategies) !
+
+
+
+### Traduction
+
+La traduction est un autre exemple de tâche séquence-à-séquence, ce qui signifie qu'un modèle encodeur-décodeur comme [BART](model_doc/bart) ou [T5](model_doc/t5) peut être utilisé pour cette tâche. Nous expliquerons ici comment BART fonctionne pour la traduction, puis vous pourrez découvrir comment affiner T5.
+
+BART adapte le modèle à la traduction en ajoutant un encodeur séparé, initialisé aléatoirement, pour mapper la langue source en une entrée qui peut être décodée dans la langue cible. Les embeddings de cet encodeur sont ensuite passés à l'encodeur préentraîné au lieu des embeddings de mots originaux. L'encodeur source est entraîné en mettant à jour l'encodeur source, les embeddings positionnels et les embeddings d'entrée avec la perte d'entropie croisée provenant de la sortie du modèle. Les paramètres du modèle sont figés lors de cette première étape, et tous les paramètres du modèle sont entraînés ensemble lors de la deuxième étape.
+
+BART a été suivi par une version multilingue, mBART, qui est spécifiquement conçue pour la traduction et préentraînée sur de nombreuses langues différentes.
+
+Prêt à essayer la traduction ? Consultez notre [guide complet sur la traduction](tasks/translation) pour apprendre à affiner T5 et l'utiliser pour l'inférence !
+
+
+
+Pour plus d'informations sur la génération de texte, consultez le guide sur les [stratégies de génération de texte](generation_strategies) !
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/tutoriel_pipeline.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/tutoriel_pipeline.md
new file mode 100644
index 0000000000000000000000000000000000000000..d398f2c0f0f51b8cdb3c350a1c431f1a2a6d3de3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/fr/tutoriel_pipeline.md
@@ -0,0 +1,313 @@
+
+
+# Pipelines pour l'inférence
+
+L'objet [`pipeline`] rend simple l'utilisation de n'importe quel modèle du [Hub](https://huggingface.co/models) pour l'inférence sur n'importe quelle langue, tâches de vision par ordinateur, d'audio et multimodales. Même si vous n'avez pas d'expérience avec une modalité spécifique ou si vous n'êtes pas familier avec le code ci-dessous des modèles, vous pouvez toujours les utiliser pour l'inférence avec la [`pipeline`] ! Ce tutoriel vous apprendra à :
+
+* Utiliser un [`pipeline`] pour l'inférence.
+* Utiliser un tokenizer ou modèle spécifique.
+* Utiliser un [`pipeline`] pour des tâches audio, de vision et multimodales.
+
+
+
+Consultez la documentation du [`pipeline`] pour une liste complète des tâches prises en charge et des paramètres disponibles.
+
+
+
+## Utilisation du pipeline
+
+Bien que chaque tâche ait son propre [`pipeline`], il est plus simple d'utiliser le [`pipeline`] générale qui inclut tous les pipelines spécifiques aux différentes tâches. Cette approche charge automatiquement un modèle par défaut et une classe de prétraitement adaptée à votre tâche, simplifiant ainsi votre utilisation. Prenons l'exemple de l'utilisation du [`pipeline`] pour la reconnaissance automatique de la parole (ASR) ou de la transcription de la parole en texte.
+
+1. Commencez par créer un [`pipeline`] et spécifiez la tâche d'inférence :
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline(task="automatic-speech-recognition")
+```
+
+2. Passez votre entrée au [`pipeline`]. Dans le cas de la reconnaissance vocale, il s'agit d'un fichier audio :
+
+```py
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': 'I HAVE A DREAM BUT ONE DAY THIS NATION WILL RISE UP LIVE UP THE TRUE MEANING OF ITS TREES'}
+```
+
+Pas le résultat que vous aviez en tête ? Consultez certains des [modèles de reconnaissance vocale automatique les plus téléchargés](https://huggingface.co/models?pipeline_tag=automatic-speech-recognition&sort=trending)
+sur le Hub pour voir si vous pouvez obtenir une meilleure transcription.
+
+Essayons le modèle [Whisper large-v2](https://huggingface.co/openai/whisper-large) de OpenAI. Whisper a été publié 2 ans après Wav2Vec2 et a été entraîné sur près de 10 fois plus de données. En tant que tel, il surpasse Wav2Vec2 sur la plupart des benchmarks en aval. Il a également l'avantage supplémentaire de prédire la ponctuation et la casse, ce qui n'est pas possible avec Wav2Vec2.
+
+Essayons-le ici pour voir comment il fonctionne :
+
+```py
+>>> transcriber = pipeline(model="openai/whisper-large-v2")
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+Maintenant, ce résultat semble plus précis ! Pour une comparaison approfondie entre Wav2Vec2 et Whisper, consultez le [cours Audio Transformers](https://huggingface.co/learn/audio-course/chapter5/asr_models).
+Nous vous encourageons vraiment à consulter le Hub pour des modèles dans différentes langues, des modèles spécialisés dans votre domaine, et plus encore.
+Vous pouvez consulter et comparer les résultats des modèles directement depuis votre navigateur sur le Hub pour voir s'ils conviennent ou gèrent mieux les cas particuliers que d'autres.
+Et si vous ne trouvez pas de modèle pour votre cas d'utilisation, vous pouvez toujours commencer à [entraîner](training) le vôtre !
+
+Si vous avez plusieurs entrées, vous pouvez passer votre entrée sous forme de liste :
+
+```py
+transcriber(
+ [
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac",
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/1.flac",
+ ]
+)
+```
+
+Les pipelines sont excellents pour l'expérimentation car passer d'un modèle à un autre est trivial ; cependant, il existe des moyens de les optimiser pour des charges de travail plus importantes que l'expérimentation. Consultez les guides suivants qui expliquent comment itérer sur des ensembles de données complets ou utiliser des pipelines dans un serveur web :
+de la documentation :
+* [Utilisation des pipelines sur un ensemble de données](#using-pipelines-on-a-dataset)
+* [Utilisation des pipelines pour un serveur web](./pipeline_webserver)
+
+## Paramètres
+
+[`pipeline`] prend en charge de nombreux paramètres ; certains sont spécifiques à la tâche et d'autres sont généraux pour tous les pipelines.
+En général, vous pouvez spécifier les paramètres où vous le souhaitez :
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", my_parameter=1)
+
+out = transcriber(...) # This will use `my_parameter=1`.
+out = transcriber(..., my_parameter=2) # This will override and use `my_parameter=2`.
+out = transcriber(...) # This will go back to using `my_parameter=1`.
+```
+
+Voyons 3 paramètres importants :
+
+### Device
+
+Si vous utilisez `device=n`, le pipeline met automatiquement le modèle sur l'appareil spécifié.
+Cela fonctionnera que vous utilisiez PyTorch ou Tensorflow.
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", device=0)
+```
+
+Si le modèle est trop grand pour un seul GPU et que vous utilisez PyTorch, vous pouvez définir `device_map="auto"` pour déterminer automatiquement comment charger et stocker les poids du modèle. L'utilisation de l'argument `device_map` nécessite le package 🤗 [Accelerate](https://huggingface.co/docs/accelerate) :
+
+```bash
+pip install --upgrade accelerate
+```
+
+Le code suivant charge et stocke automatiquement les poids du modèle sur plusieurs appareils :
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", device_map="auto")
+```
+
+Notez que si `device_map="auto"` est passé, il n'est pas nécessaire d'ajouter l'argument `device=device` lors de l'instanciation de votre `pipeline` car vous pourriez rencontrer des comportements inattendus !
+
+### Batch size
+
+Par défaut, les pipelines ne feront pas d'inférence en batch pour des raisons expliquées en détail [ici](https://huggingface.co/docs/transformers/main_classes/pipelines#pipeline-batching). La raison est que le batching n'est pas nécessairement plus rapide, et peut en fait être beaucoup plus lent dans certains cas.
+
+Mais si cela fonctionne dans votre cas d'utilisation, vous pouvez utiliser :
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", device=0, batch_size=2)
+audio_filenames = [f"https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/{i}.flac" for i in range(1, 5)]
+texts = transcriber(audio_filenames)
+```
+
+Cela exécute le pipeline sur les 4 fichiers audio fournis, mais les passera par batch de 2 au modèle (qui est sur un GPU, où le batching est plus susceptible d'aider) sans nécessiter de code supplémentaire de votre part.
+La sortie doit toujours correspondre à ce que vous auriez reçu sans batching. Il s'agit uniquement d'un moyen de vous aider à obtenir plus de vitesse avec un pipeline.
+
+Les pipelines peuvent également atténuer certaines des complexités du batching car, pour certains pipelines, un seul élément (comme un long fichier audio) doit être divisé en plusieurs parties pour être traité par un modèle. Le pipeline effectue ce [*batching par morceaux*](./main_classes/pipelines#pipeline-chunk-batching) pour vous.
+
+### Paramètres spécifiques à la tâche
+
+Toutes les tâches fournissent des paramètres spécifiques à la tâche qui permettent une flexibilité et des options supplémentaires pour vous aider à accomplir votre travail.
+Par exemple, la méthode [`transformers.AutomaticSpeechRecognitionPipeline.__call__`] dispose d'un paramètre `return_timestamps` qui semble prometteur pour le sous-titrage des vidéos :
+
+```py
+>>> transcriber = pipeline(model="openai/whisper-large-v2", return_timestamps=True)
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.', 'chunks': [{'timestamp': (0.0, 11.88), 'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its'}, {'timestamp': (11.88, 12.38), 'text': ' creed.'}]}
+```
+
+Comme vous pouvez le voir, le modèle a inféré le texte et a également indiqué **quand** les différentes phrases ont été prononcées.
+
+Il existe de nombreux paramètres disponibles pour chaque tâche, alors consultez la référence API de chaque tâche pour voir ce que vous pouvez ajuster !
+Par exemple, le [`~transformers.AutomaticSpeechRecognitionPipeline`] dispose d'un paramètre `chunk_length_s` qui est utile pour travailler sur des fichiers audio très longs (par exemple, le sous-titrage de films entiers ou de vidéos d'une heure) qu'un modèle ne peut généralement pas gérer seul :
+
+```python
+>>> transcriber = pipeline(model="openai/whisper-large-v2", chunk_length_s=30)
+>>> transcriber("https://huggingface.co/datasets/reach-vb/random-audios/resolve/main/ted_60.wav")
+{'text': " So in college, I was a government major, which means I had to write a lot of papers. Now, when a normal student writes a paper, they might spread the work out a little like this. So, you know. You get started maybe a little slowly, but you get enough done in the first week that with some heavier days later on, everything gets done and things stay civil. And I would want to do that like that. That would be the plan. I would have it all ready to go, but then actually the paper would come along, and then I would kind of do this. And that would happen every single paper. But then came my 90-page senior thesis, a paper you're supposed to spend a year on. I knew for a paper like that, my normal workflow was not an option, it was way too big a project. So I planned things out and I decided I kind of had to go something like this. This is how the year would go. So I'd start off light and I'd bump it up"}
+```
+
+Si vous ne trouvez pas un paramètre qui vous aiderait vraiment, n'hésitez pas à [le demander](https://github.com/huggingface/transformers/issues/new?assignees=&labels=feature&template=feature-request.yml) !
+
+## Utilisation des pipelines sur un ensemble de données
+
+Le pipeline peut également exécuter des inférences sur un grand ensemble de données. Le moyen le plus simple que nous recommandons pour cela est d'utiliser un itérateur :
+
+```py
+def data():
+ for i in range(1000):
+ yield f"My example {i}"
+
+
+pipe = pipeline(model="openai-community/gpt2", device=0)
+generated_characters = 0
+for out in pipe(data()):
+ generated_characters += len(out[0]["generated_text"])
+```
+
+
+L'itérateur `data()` génère chaque résultat, et le pipeline reconnaît automatiquement que l'entrée est itérable et commencera à récupérer les données tout en continuant à les traiter sur le GPU (cela utilise [DataLoader](https://pytorch.org/docs/stable/data.html#torch.utils.data.DataLoader) sous le capot).
+C'est important car vous n'avez pas besoin d'allouer de mémoire pour l'ensemble de données complet et vous pouvez alimenter le GPU aussi rapidement que possible.
+
+Étant donné que le lotissement pourrait accélérer les choses, il peut être utile d'essayer de régler le paramètre `batch_size` ici.
+
+La façon la plus simple d'itérer sur un ensemble de données est d'en charger un depuis 🤗 [Datasets](https://github.com/huggingface/datasets) :
+
+```py
+# KeyDataset is a util that will just output the item we're interested in.
+from transformers.pipelines.pt_utils import KeyDataset
+from datasets import load_dataset
+
+pipe = pipeline(model="hf-internal-testing/tiny-random-wav2vec2", device=0)
+dataset = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation[:10]")
+
+for out in pipe(KeyDataset(dataset, "audio")):
+ print(out)
+```
+
+## Utilisation des pipelines pour un serveur web
+
+
+Créer un moteur d'inférence est un sujet complexe qui mérite sa propre page.
+
+
+[Lien](./pipeline_webserver)
+
+## Pipeline de vision
+
+Utiliser un [`pipeline`] pour les tâches de vision est pratiquement identique.
+
+Spécifiez votre tâche et passez votre image au classificateur. L'image peut être un lien, un chemin local ou une image encodée en base64. Par exemple, quelle espèce de chat est montrée ci-dessous ?
+
+
+
+```py
+>>> from transformers import pipeline
+
+>>> vision_classifier = pipeline(model="google/vit-base-patch16-224")
+>>> preds = vision_classifier(
+... images="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4335, 'label': 'lynx, catamount'}, {'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}, {'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}, {'score': 0.0239, 'label': 'Egyptian cat'}, {'score': 0.0229, 'label': 'tiger cat'}]
+```
+
+
+## Pipeline de texte
+
+Utiliser un [`pipeline`] pour les tâches de NLP est pratiquement identique.
+
+```py
+>>> from transformers import pipeline
+
+>>> # This model is a `zero-shot-classification` model.
+>>> # It will classify text, except you are free to choose any label you might imagine
+>>> classifier = pipeline(model="facebook/bart-large-mnli")
+>>> classifier(
+... "I have a problem with my iphone that needs to be resolved asap!!",
+... candidate_labels=["urgent", "not urgent", "phone", "tablet", "computer"],
+... )
+{'sequence': 'I have a problem with my iphone that needs to be resolved asap!!', 'labels': ['urgent', 'phone', 'computer', 'not urgent', 'tablet'], 'scores': [0.504, 0.479, 0.013, 0.003, 0.002]}
+```
+
+
+## Pipeline multimodal
+
+Le [`pipeline`] prend en charge plus d'une modalité. Par exemple, une tâche de réponse à des questions visuelles (VQA) combine texte et image. N'hésitez pas à utiliser n'importe quel lien d'image que vous aimez et une question que vous souhaitez poser à propos de l'image. L'image peut être une URL ou un chemin local vers l'image.
+
+Par exemple, si vous utilisez cette [image de facture](https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png) :
+
+```py
+>>> from transformers import pipeline
+
+>>> vqa = pipeline(model="impira/layoutlm-document-qa")
+>>> output = vqa(
+... image="https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png",
+... question="What is the invoice number?",
+... )
+>>> output[0]["score"] = round(output[0]["score"], 3)
+>>> output
+[{'score': 0.425, 'answer': 'us-001', 'start': 16, 'end': 16}]
+```
+
+
+
+Pour exécuter l'exemple ci-dessus, vous devez avoir [`pytesseract`](https://pypi.org/project/pytesseract/) installé en plus de 🤗 Transformers :
+
+```bash
+sudo apt install -y tesseract-ocr
+pip install pytesseract
+```
+
+
+
+## Utilisation de `pipeline` sur de grands modèles avec 🤗 `accelerate` :
+
+Vous pouvez facilement exécuter `pipeline` sur de grands modèles en utilisant 🤗 `accelerate` ! Assurez-vous d'abord d'avoir installé `accelerate` avec `pip install accelerate`.
+
+Chargez d'abord votre modèle en utilisant `device_map="auto"` ! Nous utiliserons `facebook/opt-1.3b` pour notre exemple.
+
+```py
+# pip install accelerate
+import torch
+from transformers import pipeline
+
+pipe = pipeline(model="facebook/opt-1.3b", torch_dtype=torch.bfloat16, device_map="auto")
+output = pipe("This is a cool example!", do_sample=True, top_p=0.95)
+```
+Vous pouvez également passer des modèles chargés en 8 bits si vous installez `bitsandbytes` et ajoutez l'argument `load_in_8bit=True`
+Notez que vous pouvez remplacer le point de contrôle par n'importe quel modèle.
+
+```py
+# pip install accelerate bitsandbytes
+import torch
+from transformers import pipeline
+
+pipe = pipeline(model="facebook/opt-1.3b", device_map="auto", model_kwargs={"load_in_8bit": True})
+output = pipe("This is a cool example!", do_sample=True, top_p=0.95)
+```
+
+## Création de démonstrations web à partir de pipelines avec `gradio`
+
+Hugging Face prenant en charge le chargement de grands modèles, comme BLOOM.
+Les pipelines sont automatiquement pris en charge dans [Gradio](https://github.com/gradio-app/gradio/), une bibliothèque qui facilite la création d'applications d'apprentissage automatique belles et conviviales sur le web. Tout d'abord, assurez-vous que Gradio est installé :
+
+```
+pip install gradio
+```
+
+Ensuite, vous pouvez créer une démonstration web autour d'un pipeline de classification d'images (ou tout autre pipeline) en une seule ligne de code en appelant la fonction [`Interface.from_pipeline`](https://www.gradio.app/docs/interface#interface-from-pipeline) de Gradio pour lancer le pipeline. Cela crée une interface intuitive de glisser-déposer dans votre navigateur :
+
+```py
+from transformers import pipeline
+import gradio as gr
+
+pipe = pipeline("image-classification", model="google/vit-base-patch16-224")
+
+gr.Interface.from_pipeline(pipe).launch()
+```
+
+
+
+
+Par défaut, la démonstration web s'exécute sur un serveur local. Si vous souhaitez la partager avec d'autres, vous pouvez générer un lien public temporaire en définissant `share=True` dans `launch()`. Vous pouvez également héberger votre démonstration sur [Hugging Face Spaces](https://huggingface.co/spaces) pour obtenir un lien permanent.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/hi/_toctree.yml b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/hi/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..72759457a5c83a57620984bce73695b989f41cba
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/hi/_toctree.yml
@@ -0,0 +1,7 @@
+- sections:
+ - local: pipeline_tutorial
+ title: पाइपलाइनों के साथ अनुमान चलाएँ
+ - local: accelerate
+ title: 🤗 Accelerate के साथ वितरित प्रशिक्षण सेट करें
+ - local: tflite
+ title: TFLite में निर्यात करें
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/hi/accelerate.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/hi/accelerate.md
new file mode 100644
index 0000000000000000000000000000000000000000..3d568217a1299b179d28804660bf3a8124bbaa45
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/hi/accelerate.md
@@ -0,0 +1,136 @@
+
+
+# वितरित प्रशिक्षण के साथ 🤗 Accelerate
+
+जैसे-जैसे मॉडल बड़े होते हैं, समानांतरता सीमित हार्डवेयर पर बड़े मॉडल को प्रशिक्षित करने और प्रशिक्षण की गति को कई आदेशों के आकार में तेज करने के लिए एक रणनीति के रूप में उभरी है। हगिंग फेस में, हमने उपयोगकर्ताओं को किसी भी प्रकार के वितरित सेटअप पर 🤗 ट्रांसफार्मर्स मॉडल को आसानी से प्रशिक्षित करने में मदद करने के लिए [🤗 Accelerate](https://huggingface.co/docs/accelerate) पुस्तकालय बनाया है, चाहे वह एक मशीन पर कई GPU हों या कई मशीनों में कई GPU। इस ट्यूटोरियल में, जानें कि अपने मूल PyTorch प्रशिक्षण लूप को कैसे अनुकूलित किया जाए ताकि वितरित वातावरण में प्रशिक्षण सक्षम हो सके।
+
+## सेटअप
+
+🤗 Accelerate स्थापित करके शुरू करें:
+
+```bash
+pip install accelerate
+```
+
+फिर एक [`~accelerate.Accelerator`] ऑब्जेक्ट आयात करें और बनाएं। [`~accelerate.Accelerator`] स्वचालित रूप से आपके वितरित सेटअप के प्रकार का पता लगाएगा और प्रशिक्षण के लिए सभी आवश्यक घटकों को प्रारंभ करेगा। आपको अपने मॉडल को किसी डिवाइस पर स्पष्ट रूप से रखने की आवश्यकता नहीं है।
+
+```py
+>>> from accelerate import Accelerator
+
+>>> accelerator = Accelerator()
+```
+
+## तेजी लाने की तैयारी
+
+अगला कदम सभी प्रासंगिक प्रशिक्षण वस्तुओं को [`~accelerate.Accelerator.prepare`] विधि में पास करना है। इसमें आपके प्रशिक्षण और मूल्यांकन DataLoaders, एक मॉडल और एक ऑप्टिमाइज़र शामिल हैं:
+
+```py
+>>> train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
+... train_dataloader, eval_dataloader, model, optimizer
+... )
+```
+
+## बैकवर्ड
+
+अंतिम जोड़ यह है कि आपके प्रशिक्षण लूप में सामान्य `loss.backward()` को 🤗 Accelerate के [`~accelerate.Accelerator.backward`] विधि से बदलें:
+
+```py
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... outputs = model(**batch)
+... loss = outputs.loss
+... accelerator.backward(loss)
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+जैसा कि आप निम्नलिखित कोड में देख सकते हैं, आपको वितरित प्रशिक्षण सक्षम करने के लिए अपने प्रशिक्षण लूप में केवल चार अतिरिक्त कोड की पंक्तियाँ जोड़ने की आवश्यकता है!
+
+```diff
++ from accelerate import Accelerator
+ from transformers import AdamW, AutoModelForSequenceClassification, get_scheduler
+
++ accelerator = Accelerator()
+
+ model = AutoModelForSequenceClassification.from_pretrained(checkpoint, num_labels=2)
+ optimizer = AdamW(model.parameters(), lr=3e-5)
+
+- device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+- model.to(device)
+
++ train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
++ train_dataloader, eval_dataloader, model, optimizer
++ )
+
+ num_epochs = 3
+ num_training_steps = num_epochs * len(train_dataloader)
+ lr_scheduler = get_scheduler(
+ "linear",
+ optimizer=optimizer,
+ num_warmup_steps=0,
+ num_training_steps=num_training_steps
+ )
+
+ progress_bar = tqdm(range(num_training_steps))
+
+ model.train()
+ for epoch in range(num_epochs):
+ for batch in train_dataloader:
+- batch = {k: v.to(device) for k, v in batch.items()}
+ outputs = model(**batch)
+ loss = outputs.loss
+- loss.backward()
++ accelerator.backward(loss)
+
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ progress_bar.update(1)
+```
+
+## प्रशिक्षण
+
+एक बार जब आपने प्रासंगिक कोड की पंक्तियाँ जोड़ दी हैं, तो अपने प्रशिक्षण को स्क्रिप्ट या कोलैबोरेटरी जैसे नोटबुक में लॉन्च करें।
+
+### स्क्रिप्ट के साथ प्रशिक्षण
+
+यदि आप स्क्रिप्ट से अपना प्रशिक्षण चला रहे हैं, तो एक कॉन्फ़िगरेशन फ़ाइल बनाने और सहेजने के लिए निम्नलिखित कमांड चलाएँ:
+
+```bash
+accelerate config
+```
+
+फिर अपने प्रशिक्षण को इस तरह लॉन्च करें:
+
+```bash
+accelerate launch train.py
+```
+
+### नोटबुक के साथ प्रशिक्षण
+
+🤗 Accelerate एक नोटबुक में भी चल सकता है यदि आप Colaboratory के TPU का उपयोग करने की योजना बना रहे हैं। प्रशिक्षण के लिए जिम्मेदार सभी कोड को एक फ़ंक्शन में लपेटें, और इसे [`~accelerate.notebook_launcher`] में पास करें:
+
+```py
+>>> from accelerate import notebook_launcher
+
+>>> notebook_launcher(training_function)
+```
+
+🤗 Accelerate और इसकी समृद्ध सुविधाओं के बारे में अधिक जानकारी के लिए, [दस्तावेज़ीकरण](https://huggingface.co/docs/accelerate) देखें।
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/hi/pipeline_tutorial.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/hi/pipeline_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..d20d5d617a972763eb864992ee63fd32887fdd9a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/hi/pipeline_tutorial.md
@@ -0,0 +1,319 @@
+
+
+# अनुमान के लिए पाइपलाइन
+
+[`pipeline`] किसी भी भाषा, कंप्यूटर दृष्टि, भाषण और मल्टीमॉडल कार्यों पर अनुमान लगाने के लिए [Hub](https://huggingface.co/models) से किसी भी मॉडल का उपयोग करना आसान बनाता है। भले ही आपके पास किसी विशिष्ट तौर-तरीके का अनुभव न हो या आप मॉडलों के पीछे अंतर्निहित कोड से परिचित न हों, फिर भी आप [`pipeline`] के अनुमान के लिए उनका उपयोग कर सकते हैं! यह ट्यूटोरियल आपको ये सिखाएगा:
+
+* अनुमान के लिए [`pipeline`] का उपयोग करें।
+* एक विशिष्ट टोकननाइज़र या मॉडल का उपयोग करें।
+* ऑडियो, विज़न और मल्टीमॉडल कार्यों के लिए [`pipeline`] का उपयोग करें।
+
+
+
+समर्थित कार्यों और उपलब्ध मापदंडों की पूरी सूची के लिए [`pipeline`] दस्तावेज़ पर एक नज़र डालें।
+
+
+
+## पाइपलाइन का उपयोग
+
+जबकि प्रत्येक कार्य में एक संबद्ध [`pipeline`] होता है, सामान्य [`pipeline`] अमूर्त का उपयोग करना आसान होता है जिसमें शामिल होता है
+सभी कार्य-विशिष्ट पाइपलाइनें। [`pipeline`] स्वचालित रूप से एक डिफ़ॉल्ट मॉडल और सक्षम प्रीप्रोसेसिंग क्लास लोड करता है
+आपके कार्य के लिए अनुमान का. आइए स्वचालित वाक् पहचान (एएसआर) के लिए [`pipeline`] का उपयोग करने का उदाहरण लें, या
+वाक्-से-पाठ.
+
+
+1. एक [`pipeline`] बनाकर प्रारंभ करें और अनुमान कार्य निर्दिष्ट करें:
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline(task="automatic-speech-recognition")
+```
+
+2. अपना इनपुट [`pipeline`] पर भेजें। वाक् पहचान के मामले में, यह एक ऑडियो इनपुट फ़ाइल है:
+
+```py
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': 'I HAVE A DREAM BUT ONE DAY THIS NATION WILL RISE UP LIVE UP THE TRUE MEANING OF ITS TREES'}
+```
+
+क्या वह परिणाम नहीं जो आपके मन में था? कुछ [सबसे अधिक डाउनलोड किए गए स्वचालित वाक् पहचान मॉडल](https://huggingface.co/models?pipeline_tag=automatic-speech-recognition&sort=trending) देखें
+यह देखने के लिए हब पर जाएं कि क्या आपको बेहतर ट्रांस्क्रिप्शन मिल सकता है।
+
+आइए OpenAI से [व्हिस्पर लार्ज-v2](https://huggingface.co/openai/whisper-large) मॉडल आज़माएं। व्हिस्पर जारी किया गया
+Wav2Vec2 की तुलना में 2 साल बाद, और लगभग 10 गुना अधिक डेटा पर प्रशिक्षित किया गया था। इस प्रकार, यह अधिकांश डाउनस्ट्रीम पर Wav2Vec2 को मात देता है
+बेंचमार्क. इसमें विराम चिह्न और आवरण की भविष्यवाणी करने का अतिरिक्त लाभ भी है, जिनमें से कोई भी संभव नहीं है
+Wav2Vec2.
+
+आइए इसे यहां आज़माकर देखें कि यह कैसा प्रदर्शन करता है:
+
+```py
+>>> transcriber = pipeline(model="openai/whisper-large-v2")
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+अब यह परिणाम अधिक सटीक दिखता है! Wav2Vec2 बनाम व्हिस्पर पर गहन तुलना के लिए, [ऑडियो ट्रांसफॉर्मर्स कोर्स](https://huggingface.co/learn/audio-course/chapter5/asr_models) देखें।
+हम वास्तव में आपको विभिन्न भाषाओं में मॉडल, आपके क्षेत्र में विशेषीकृत मॉडल और बहुत कुछ के लिए हब की जांच करने के लिए प्रोत्साहित करते हैं।
+आप हब पर सीधे अपने ब्राउज़र से मॉडल परिणामों की जांच और तुलना कर सकते हैं कि यह फिट बैठता है या नहीं
+अन्य मामलों की तुलना में कोने के मामलों को बेहतर ढंग से संभालता है।
+और यदि आपको अपने उपयोग के मामले के लिए कोई मॉडल नहीं मिलता है, तो आप हमेशा अपना खुद का [प्रशिक्षण](training) शुरू कर सकते हैं!
+
+यदि आपके पास कई इनपुट हैं, तो आप अपने इनपुट को एक सूची के रूप में पास कर सकते हैं:
+
+```py
+transcriber(
+ [
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac",
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/1.flac",
+ ]
+)
+```
+
+पाइपलाइनें प्रयोग के लिए बहुत अच्छी हैं क्योंकि एक मॉडल से दूसरे मॉडल पर स्विच करना मामूली काम है; हालाँकि, प्रयोग की तुलना में बड़े कार्यभार के लिए उन्हें अनुकूलित करने के कुछ तरीके हैं। संपूर्ण डेटासेट पर पुनरावृत्ति करने या वेबसर्वर में पाइपलाइनों का उपयोग करने के बारे में निम्नलिखित मार्गदर्शिकाएँ देखें:
+दस्तावेज़ों में से:
+* [डेटासेट पर पाइपलाइनों का उपयोग करना](#using-pipelines-on-a-dataset)
+* [वेबसर्वर के लिए पाइपलाइनों का उपयोग करना](./pipeline_webserver)
+
+## प्राचल
+
+[`pipeline`] कई मापदंडों का समर्थन करता है; कुछ कार्य विशिष्ट हैं, और कुछ सभी पाइपलाइनों के लिए सामान्य हैं।
+सामान्य तौर पर, आप अपनी इच्छानुसार कहीं भी पैरामीटर निर्दिष्ट कर सकते हैं:
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", my_parameter=1)
+
+out = transcriber(...) # This will use `my_parameter=1`.
+out = transcriber(..., my_parameter=2) # This will override and use `my_parameter=2`.
+out = transcriber(...) # This will go back to using `my_parameter=1`.
+```
+
+आइए 3 महत्वपूर्ण बातों पर गौर करें:
+
+### उपकरण
+
+यदि आप `device=0` का उपयोग करते हैं, तो पाइपलाइन स्वचालित रूप से मॉडल को निर्दिष्ट डिवाइस पर डाल देती है।
+यह इस पर ध्यान दिए बिना काम करेगा कि आप PyTorch या Tensorflow का उपयोग कर रहे हैं या नहीं।
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", device=0)
+```
+
+यदि मॉडल एकल GPU के लिए बहुत बड़ा है और आप PyTorch का उपयोग कर रहे हैं, तो आप `device_map="auto"` को स्वचालित रूप से सेट कर सकते हैं
+निर्धारित करें कि मॉडल वज़न को कैसे लोड और संग्रहीत किया जाए। `device_map` तर्क का उपयोग करने के लिए 🤗 [Accelerate](https://huggingface.co/docs/accelerate) की आवश्यकता होती है
+पैकेट:
+
+```bash
+pip install --upgrade accelerate
+```
+
+निम्नलिखित कोड स्वचालित रूप से सभी डिवाइसों में मॉडल भार को लोड और संग्रहीत करता है:
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", device_map="auto")
+```
+
+ध्यान दें कि यदि `device_map='auto'` पारित हो गया है, तो अपनी `pipeline` को चालू करते समय `device=device` तर्क जोड़ने की कोई आवश्यकता नहीं है क्योंकि आपको कुछ अप्रत्याशित व्यवहार का सामना करना पड़ सकता है!
+
+### बैच का आकार
+
+डिफ़ॉल्ट रूप से, पाइपलाइनें [यहां](https://huggingface.co/docs/transformers/main_classes/pipelines#pipeline-batching) विस्तार से बताए गए कारणों के लिए बैच अनुमान नहीं लगाएंगी। इसका कारण यह है कि बैचिंग आवश्यक रूप से तेज़ नहीं है, और वास्तव में कुछ मामलों में काफी धीमी हो सकती है।
+
+लेकिन अगर यह आपके उपयोग के मामले में काम करता है, तो आप इसका उपयोग कर सकते हैं:
+
+```py
+transcriber = pipeline(model="openai/whisper-large-v2", device=0, batch_size=2)
+audio_filenames = [f"https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/{i}.flac" for i in range(1, 5)]
+texts = transcriber(audio_filenames)
+```
+
+यह प्रदान की गई 4 ऑडियो फाइलों पर पाइपलाइन चलाता है, लेकिन यह उन्हें 2 के बैच में पास करेगा
+आपसे किसी और कोड की आवश्यकता के बिना मॉडल (जो एक जीपीयू पर है, जहां बैचिंग से मदद मिलने की अधिक संभावना है) पर जाएं।
+आउटपुट हमेशा उसी से मेल खाना चाहिए जो आपको बैचिंग के बिना प्राप्त हुआ होगा। इसका उद्देश्य केवल पाइपलाइन से अधिक गति प्राप्त करने में आपकी सहायता करना है।
+
+पाइपलाइनें बैचिंग की कुछ जटिलताओं को भी कम कर सकती हैं क्योंकि, कुछ पाइपलाइनों के लिए, एक एकल आइटम (जैसे एक लंबी ऑडियो फ़ाइल) को एक मॉडल द्वारा संसाधित करने के लिए कई भागों में विभाजित करने की आवश्यकता होती है। पाइपलाइन आपके लिए यह [*chunk batching*](./main_classes/pipelines#pipeline-chunk-batching) करती है।
+
+### कार्य विशिष्ट प्राचल
+
+सभी कार्य कार्य विशिष्ट प्राचल प्रदान करते हैं जो आपको अपना काम पूरा करने में मदद करने के लिए अतिरिक्त लचीलेपन और विकल्पों की अनुमति देते हैं।
+उदाहरण के लिए, [`transformers.AutomaticSpeechRecognitionPipeline.__call__`] विधि में एक `return_timestamps` प्राचल है जो वीडियो उपशीर्षक के लिए आशाजनक लगता है:
+
+
+```py
+>>> transcriber = pipeline(model="openai/whisper-large-v2", return_timestamps=True)
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.', 'chunks': [{'timestamp': (0.0, 11.88), 'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its'}, {'timestamp': (11.88, 12.38), 'text': ' creed.'}]}
+```
+
+जैसा कि आप देख सकते हैं, मॉडल ने पाठ का अनुमान लगाया और **when** विभिन्न वाक्यों का उच्चारण किया गया तो आउटपुट भी दिया।
+
+प्रत्येक कार्य के लिए कई प्राचल उपलब्ध हैं, इसलिए यह देखने के लिए कि आप किसके साथ छेड़छाड़ कर सकते हैं, प्रत्येक कार्य का API संदर्भ देखें!
+उदाहरण के लिए, [`~transformers.AutomaticSpeechRecognitionPipeline`] में एक `chunk_length_s` प्राचल है जो सहायक है
+वास्तव में लंबी ऑडियो फ़ाइलों पर काम करने के लिए (उदाहरण के लिए, संपूर्ण फिल्मों या घंटे-लंबे वीडियो को उपशीर्षक देना) जो आमतौर पर एक मॉडल होता है
+अपने आप संभाल नहीं सकता:
+
+```python
+>>> transcriber = pipeline(model="openai/whisper-large-v2", chunk_length_s=30, return_timestamps=True)
+>>> transcriber("https://huggingface.co/datasets/sanchit-gandhi/librispeech_long/resolve/main/audio.wav")
+{'text': " Chapter 16. I might have told you of the beginning of this liaison in a few lines, but I wanted you to see every step by which we came. I, too, agree to whatever Marguerite wished, Marguerite to be unable to live apart from me. It was the day after the evening...
+```
+
+यदि आपको कोई ऐसा पैरामीटर नहीं मिल रहा है जो वास्तव में आपकी मदद करेगा, तो बेझिझक [अनुरोध करें](https://github.com/huggingface/transformers/issues/new?assignees=&labels=feature&template=feature-request.yml)!
+
+
+## डेटासेट पर पाइपलाइनों का उपयोग करना
+
+पाइपलाइन बड़े डेटासेट पर भी अनुमान चला सकती है। ऐसा करने का सबसे आसान तरीका हम एक पुनरावर्तक का उपयोग करने की सलाह देते हैं:
+
+```py
+def data():
+ for i in range(1000):
+ yield f"My example {i}"
+
+
+pipe = pipeline(model="openai-community/gpt2", device=0)
+generated_characters = 0
+for out in pipe(data()):
+ generated_characters += len(out[0]["generated_text"])
+```
+
+पुनरावर्तक `data()` प्रत्येक परिणाम और पाइपलाइन स्वचालित रूप से उत्पन्न करता है
+पहचानता है कि इनपुट पुनरावर्तनीय है और डेटा प्राप्त करना शुरू कर देगा
+यह इसे GPU पर प्रोसेस करना जारी रखता है (यह हुड के तहत [DataLoader](https://pytorch.org/docs/stable/data.html#torch.utils.data.DataLoader) का उपयोग करता है)।
+यह महत्वपूर्ण है क्योंकि आपको संपूर्ण डेटासेट के लिए मेमोरी आवंटित करने की आवश्यकता नहीं है
+और आप जितनी जल्दी हो सके GPU को फीड कर सकते हैं।
+
+चूंकि बैचिंग से चीज़ें तेज़ हो सकती हैं, इसलिए यहां `batch_size` प्राचल को ट्यून करने का प्रयास करना उपयोगी हो सकता है।
+
+किसी डेटासेट पर पुनरावृति करने का सबसे सरल तरीका बस एक को 🤗 [Dataset](https://github.com/huggingface/datasets/) से लोड करना है:
+
+```py
+# KeyDataset is a util that will just output the item we're interested in.
+from transformers.pipelines.pt_utils import KeyDataset
+from datasets import load_dataset
+
+pipe = pipeline(model="hf-internal-testing/tiny-random-wav2vec2", device=0)
+dataset = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation[:10]")
+
+for out in pipe(KeyDataset(dataset, "audio")):
+ print(out)
+```
+
+
+## वेबसर्वर के लिए पाइपलाइनों का उपयोग करना
+
+
+एक अनुमान इंजन बनाना एक जटिल विषय है जो अपने आप में उपयुक्त है
+पृष्ठ।
+
+
+[Link](./pipeline_webserver)
+
+## विज़न पाइपलाइन
+
+दृष्टि कार्यों के लिए [`pipeline`] का उपयोग करना व्यावहारिक रूप से समान है।
+
+अपना कार्य निर्दिष्ट करें और अपनी छवि क्लासिफायरियर को भेजें। छवि एक लिंक, एक स्थानीय पथ या बेस64-एन्कोडेड छवि हो सकती है। उदाहरण के लिए, बिल्ली की कौन सी प्रजाति नीचे दिखाई गई है?
+
+
+
+```py
+>>> from transformers import pipeline
+
+>>> vision_classifier = pipeline(model="google/vit-base-patch16-224")
+>>> preds = vision_classifier(
+... images="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4335, 'label': 'lynx, catamount'}, {'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}, {'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}, {'score': 0.0239, 'label': 'Egyptian cat'}, {'score': 0.0229, 'label': 'tiger cat'}]
+```
+
+## पाठ पाइपलाइन
+
+NLP कार्यों के लिए [`pipeline`] का उपयोग करना व्यावहारिक रूप से समान है।
+
+```py
+>>> from transformers import pipeline
+
+>>> # This model is a `zero-shot-classification` model.
+>>> # It will classify text, except you are free to choose any label you might imagine
+>>> classifier = pipeline(model="facebook/bart-large-mnli")
+>>> classifier(
+... "I have a problem with my iphone that needs to be resolved asap!!",
+... candidate_labels=["urgent", "not urgent", "phone", "tablet", "computer"],
+... )
+{'sequence': 'I have a problem with my iphone that needs to be resolved asap!!', 'labels': ['urgent', 'phone', 'computer', 'not urgent', 'tablet'], 'scores': [0.504, 0.479, 0.013, 0.003, 0.002]}
+```
+
+## बहुविध पाइपलाइन
+
+[`pipeline`] एक से अधिक तौर-तरीकों का समर्थन करती है। उदाहरण के लिए, एक दृश्य प्रश्न उत्तर (VQA) कार्य पाठ और छवि को जोड़ता है। अपनी पसंद के किसी भी छवि लिंक और छवि के बारे में कोई प्रश्न पूछने के लिए स्वतंत्र महसूस करें। छवि एक URL या छवि का स्थानीय पथ हो सकती है।
+
+उदाहरण के लिए, यदि आप इस [invoice image](https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png) का उपयोग करते हैं:
+
+```py
+>>> from transformers import pipeline
+
+>>> vqa = pipeline(model="impira/layoutlm-document-qa")
+>>> output = vqa(
+... image="https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png",
+... question="What is the invoice number?",
+... )
+>>> output[0]["score"] = round(output[0]["score"], 3)
+>>> output
+[{'score': 0.425, 'answer': 'us-001', 'start': 16, 'end': 16}]
+```
+
+
+
+ऊपर दिए गए उदाहरण को चलाने के लिए आपको 🤗 ट्रांसफॉर्मर के अलावा [`pytesseract`](https://pypi.org/project/pytesseract/) इंस्टॉल करना होगा:
+
+```bash
+sudo apt install -y tesseract-ocr
+pip install pytesseract
+```
+
+
+
+## 🤗 `त्वरण` के साथ बड़े मॉडलों पर `pipeline` का उपयोग करना:
+
+आप 🤗 `accelerate` का उपयोग करके बड़े मॉडलों पर आसानी से `pipeline` चला सकते हैं! पहले सुनिश्चित करें कि आपने `accelerate` को `pip install accelerate` के साथ इंस्टॉल किया है।
+
+सबसे पहले `device_map='auto'` का उपयोग करके अपना मॉडल लोड करें! हम अपने उदाहरण के लिए `facebook/opt-1.3b` का उपयोग करेंगे।
+
+```py
+# pip install accelerate
+import torch
+from transformers import pipeline
+
+pipe = pipeline(model="facebook/opt-1.3b", torch_dtype=torch.bfloat16, device_map="auto")
+output = pipe("This is a cool example!", do_sample=True, top_p=0.95)
+```
+
+यदि आप `bitsandbytes` इंस्टॉल करते हैं और `load_in_8bit=True` तर्क जोड़ते हैं तो आप 8-बिट लोडेड मॉडल भी पास कर सकते हैं
+
+```py
+# pip install accelerate bitsandbytes
+import torch
+from transformers import pipeline
+
+pipe = pipeline(model="facebook/opt-1.3b", device_map="auto", model_kwargs={"load_in_8bit": True})
+output = pipe("This is a cool example!", do_sample=True, top_p=0.95)
+```
+
+ध्यान दें कि आप चेकपॉइंट को किसी भी हगिंग फेस मॉडल से बदल सकते हैं जो BLOOM जैसे बड़े मॉडल लोडिंग का समर्थन करता है!
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/hi/tflite.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/hi/tflite.md
new file mode 100644
index 0000000000000000000000000000000000000000..5a84bed94266db0de5e8fa81cfcd7c1cb2a5b643
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/hi/tflite.md
@@ -0,0 +1,55 @@
+
+
+# TFLite में निर्यात करें
+
+[TensorFlow Lite](https://www.tensorflow.org/lite/guide) एक हल्का ढांचा है जो मशीन लर्निंग मॉडल को संसाधन-सीमित उपकरणों, जैसे मोबाइल फोन, एम्बेडेड सिस्टम और इंटरनेट ऑफ थिंग्स (IoT) उपकरणों पर तैनात करने के लिए है। TFLite को इन उपकरणों पर सीमित गणनात्मक शक्ति, मेमोरी और ऊर्जा खपत के साथ मॉडल को कुशलता से ऑप्टिमाइज़ और चलाने के लिए डिज़ाइन किया गया है। एक TensorFlow Lite मॉडल को एक विशेष कुशल पोर्टेबल प्रारूप में दर्शाया जाता है जिसे `.tflite` फ़ाइल एक्सटेंशन द्वारा पहचाना जाता है।
+
+🤗 Optimum में `exporters.tflite` मॉड्यूल के माध्यम से 🤗 Transformers मॉडल को TFLite में निर्यात करने की कार्यक्षमता है। समर्थित मॉडल आर्किटेक्चर की सूची के लिए, कृपया [🤗 Optimum दस्तावेज़](https://huggingface.co/docs/optimum/exporters/tflite/overview) देखें।
+
+TFLite में एक मॉडल निर्यात करने के लिए, आवश्यक निर्भरताएँ स्थापित करें:
+
+```bash
+pip install optimum[exporters-tf]
+```
+
+सभी उपलब्ध तर्कों की जांच करने के लिए, [🤗 Optimum दस्तावेज़](https://huggingface.co/docs/optimum/main/en/exporters/tflite/usage_guides/export_a_model) देखें,
+या कमांड लाइन में मदद देखें:
+
+```bash
+optimum-cli export tflite --help
+```
+
+यदि आप 🤗 Hub से एक मॉडल का चेकपॉइंट निर्यात करना चाहते हैं, उदाहरण के लिए, `google-bert/bert-base-uncased`, निम्नलिखित कमांड चलाएँ:
+
+```bash
+optimum-cli export tflite --model google-bert/bert-base-uncased --sequence_length 128 bert_tflite/
+```
+
+आपको प्रगति को दर्शाते हुए लॉग दिखाई देंगे और यह दिखाएंगे कि परिणामस्वरूप `model.tflite` कहाँ सहेजा गया है, जैसे:
+
+```bash
+Validating TFLite model...
+ -[✓] TFLite model output names match reference model (logits)
+ - Validating TFLite Model output "logits":
+ -[✓] (1, 128, 30522) matches (1, 128, 30522)
+ -[x] values not close enough, max diff: 5.817413330078125e-05 (atol: 1e-05)
+The TensorFlow Lite export succeeded with the warning: The maximum absolute difference between the output of the reference model and the TFLite exported model is not within the set tolerance 1e-05:
+- logits: max diff = 5.817413330078125e-05.
+ The exported model was saved at: bert_tflite
+```
+
+उपरोक्त उदाहरण 🤗 Hub से एक चेकपॉइंट निर्यात करने को दर्शाता है। जब एक स्थानीय मॉडल निर्यात करते हैं, तो पहले सुनिश्चित करें कि आपने मॉडल के वज़न और टोकनाइज़र फ़ाइलों को एक ही निर्देशिका (`local_path`) में सहेजा है। CLI का उपयोग करते समय, चेकपॉइंट नाम के बजाय `model` तर्क में `local_path` पास करें।
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/_config.py b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/_config.py
new file mode 100644
index 0000000000000000000000000000000000000000..72b362f9a7230a3aa8fa5ef72747bf56cec5f6b8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/_config.py
@@ -0,0 +1,15 @@
+# docstyle-ignore
+INSTALL_CONTENT = """
+# Installazione di Transformers
+! pip install transformers datasets evaluate accelerate
+# Per installare dalla fonte invece dell'ultima versione rilasciata, commenta il comando sopra e
+# rimuovi la modalità commento al comando seguente.
+# ! pip install git+https://github.com/huggingface/transformers.git
+"""
+
+notebook_first_cells = [{"type": "code", "content": INSTALL_CONTENT}]
+black_avoid_patterns = {
+ "{processor_class}": "FakeProcessorClass",
+ "{model_class}": "FakeModelClass",
+ "{object_class}": "FakeObjectClass",
+}
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/_toctree.yml b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..47d90f9a9a85c985d2233a61e1eac1f398536272
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/_toctree.yml
@@ -0,0 +1,71 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers
+ - local: quicktour
+ title: Tour rapido
+ - local: installation
+ title: Installazione
+ title: Iniziare
+- sections:
+ - local: pipeline_tutorial
+ title: Pipeline per l'inferenza
+ - local: autoclass_tutorial
+ title: Carica istanze pre-allenate con AutoClass
+ - local: preprocessing
+ title: Preprocess
+ - local: training
+ title: Fine-tuning di un modello pre-addestrato
+ - local: accelerate
+ title: Allenamento distribuito con 🤗 Accelerate
+ - local: model_sharing
+ title: Condividere un modello
+ title: Esercitazione
+- sections:
+ - local: create_a_model
+ title: Crea un'architettura personalizzata
+ - local: custom_models
+ title: Condividere modelli personalizzati
+ - local: run_scripts
+ title: Addestramento con script
+ - local: multilingual
+ title: Modelli multilingua per l'inferenza
+ - local: converting_tensorflow_models
+ title: Convertire modelli tensorflow
+ - local: serialization
+ title: Esporta modelli Transformers
+ - local: perf_train_cpu
+ title: Addestramento efficiente su CPU
+ - local: perf_train_cpu_many
+ title: Addestramento efficiente su multiple CPU
+ - local: perf_train_tpu
+ title: Addestramento su TPU
+ - local: perf_train_special
+ title: Addestramento su Hardware Specializzato
+ - local: perf_infer_cpu
+ title: Inferenza Efficiente su CPU
+ - local: perf_infer_gpu_one
+ title: Inferenza su una GPU
+ - local: perf_infer_gpu_many
+ title: Inferenza Efficiente su GPU Multiple
+ - local: perf_infer_special
+ title: Inferenza su Hardware Specializzato
+ - local: big_models
+ title: Istanziare un big model
+ - local: migration
+ title: Passaggio da pacchetti precedenti
+ - local: debugging
+ title: Debugging
+ title: Guide pratiche
+- sections:
+ - local: add_new_pipeline
+ title: Come aggiungere una pipeline a 🤗 Transformers?
+ - local: add_new_model
+ title: Come aggiungere un modello a 🤗 Transformers?
+ - local: perf_hardware
+ title: Hardware ottimizzato per l'addestramento
+ - local: community
+ title: Risorse della comunità
+ - local: pr_checks
+ title: Controlli su una Pull Request
+ title: Guide How-to
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/accelerate.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/accelerate.md
new file mode 100644
index 0000000000000000000000000000000000000000..3114613a9a7994c0c326b5deb6da428f5be9ab3a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/accelerate.md
@@ -0,0 +1,136 @@
+
+
+# Allenamento distribuito con 🤗 Accelerate
+
+La parallelizzazione è emersa come strategia per allenare modelli sempre più grandi su hardware limitato e accelerarne la velocità di allenamento di diversi ordini di magnitudine. In Hugging Face, abbiamo creato la libreria [🤗 Accelerate](https://huggingface.co/docs/accelerate) per aiutarti ad allenare in modo semplice un modello 🤗 Transformers su qualsiasi tipo di configurazione distribuita, sia che si tratti di più GPU su una sola macchina o di più GPU su più macchine. In questo tutorial, imparerai come personalizzare il training loop nativo di PyTorch per consentire l'addestramento in un ambiente distribuito.
+
+## Configurazione
+
+Inizia installando 🤗 Accelerate:
+
+```bash
+pip install accelerate
+```
+
+Poi importa e crea un oggetto [`Accelerator`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator). `Accelerator` rileverà automaticamente il tuo setup distribuito e inizializzerà tutte le componenti necessarie per l'allenamento. Non dovrai allocare esplicitamente il tuo modello su un device.
+
+```py
+>>> from accelerate import Accelerator
+
+>>> accelerator = Accelerator()
+```
+
+## Preparati ad accelerare
+
+Il prossimo passo è quello di passare tutti gli oggetti rilevanti per l'allenamento al metodo [`prepare`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator.prepare). Questo include i tuoi DataLoaders per l'allenamento e per la valutazione, un modello e un ottimizzatore:
+
+```py
+>>> train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
+... train_dataloader, eval_dataloader, model, optimizer
+... )
+```
+
+## Backward
+
+Infine, sostituisci il tipico metodo `loss.backward()` nel tuo loop di allenamento con il metodo [`backward`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator.backward) di 🤗 Accelerate:
+
+```py
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... outputs = model(**batch)
+... loss = outputs.loss
+... accelerator.backward(loss)
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+Come puoi vedere nel seguente codice, hai solo bisogno di aggiungere quattro righe in più di codice al tuo training loop per abilitare l'allenamento distribuito!
+
+```diff
++ from accelerate import Accelerator
+ from transformers import AdamW, AutoModelForSequenceClassification, get_scheduler
+
++ accelerator = Accelerator()
+
+ model = AutoModelForSequenceClassification.from_pretrained(checkpoint, num_labels=2)
+ optimizer = AdamW(model.parameters(), lr=3e-5)
+
+- device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+- model.to(device)
+
++ train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
++ train_dataloader, eval_dataloader, model, optimizer
++ )
+
+ num_epochs = 3
+ num_training_steps = num_epochs * len(train_dataloader)
+ lr_scheduler = get_scheduler(
+ "linear",
+ optimizer=optimizer,
+ num_warmup_steps=0,
+ num_training_steps=num_training_steps
+ )
+
+ progress_bar = tqdm(range(num_training_steps))
+
+ model.train()
+ for epoch in range(num_epochs):
+ for batch in train_dataloader:
+- batch = {k: v.to(device) for k, v in batch.items()}
+ outputs = model(**batch)
+ loss = outputs.loss
+- loss.backward()
++ accelerator.backward(loss)
+
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ progress_bar.update(1)
+```
+
+## Allenamento
+
+Una volta che hai aggiunto le righe di codice rilevanti, lancia il tuo allenamento in uno script o in un notebook come Colaboratory.
+
+### Allenamento con uno script
+
+Se stai eseguendo il tuo allenamento da uno script, esegui il comando seguente per creare e salvare un file di configurazione:
+
+```bash
+accelerate config
+```
+
+Poi lancia il tuo allenamento con:
+
+```bash
+accelerate launch train.py
+```
+
+### Allenamento con un notebook
+
+La libreria 🤗 Accelerate può anche essere utilizzata in un notebook se stai pianificando di utilizzare le TPU di Colaboratory. Inserisci tutto il codice legato all'allenamento in una funzione, e passala al `notebook_launcher`:
+
+```py
+>>> from accelerate import notebook_launcher
+
+>>> notebook_launcher(training_function)
+```
+
+Per maggiori informazioni relative a 🤗 Accelerate e le sue numerose funzionalità, fai riferimento alla [documentazione](https://huggingface.co/docs/accelerate).
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/add_new_model.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/add_new_model.md
new file mode 100644
index 0000000000000000000000000000000000000000..9403aa46a2183bfcffa555d9804045eb0e028d9d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/add_new_model.md
@@ -0,0 +1,780 @@
+
+
+# Come aggiungere un modello a 🤗 Transformers?
+
+Aggiungere un nuovo modello é spesso difficile e richiede una profonda conoscenza della libreria 🤗 Transformers e anche
+della repository originale del modello. A Hugging Face cerchiamo di dare alla community sempre piú poteri per aggiungere
+modelli independentemente. Quindi, per alcuni nuovi modelli che la community vuole aggiungere a 🤗 Transformers, abbiamo
+creato una specifica *call-for-model-addition* che spiega passo dopo passo come aggiungere il modello richiesto. Con
+questo *call-for-model-addition* vogliamo insegnare a volenterosi e esperti collaboratori della community come implementare
+un modello in 🤗 Transformers.
+
+Se questo é qualcosa che può interessarvi, siete liberi di controllare l'attuale “calls-for-model-addition” [qui](https://github.com/huggingface/transformers/tree/main/templates/adding_a_new_model/open_model_proposals/README.md)
+e contattarci.
+
+Se il modello sarà selezionato, allora potrete lavorare insieme a un membro di Hugging Face per integrare il modello in 🤗
+Transformers. Così facendo, ci guadagnerai in una comprensione totale, sia teorica che pratica, del modello proposto. Inoltre,
+sarai l'artefice di un importante contributo open-source a 🤗 Transformers. Durante l'implementazione avrai l'opportunità di:
+
+- ottenere più comprensione delle best practices in open-source
+- capire i principi di design di una della librerie NLP più popolari
+- capire come efficientemente testare complessi modelli NLP
+- capire come integrare utilit Python come `black`, `ruff`, `make fix-copies` in una libreria per garantire sempre di avere un codice leggibile e pulito
+
+Siamo anche contenti se vuoi aggiungere un modello che non può essere trovato nella cartella “calls-for-model-addition”.
+Le seguenti sezioni spiegano in dettaglio come aggiungere un nuovo modello. Può anche essere molto utile controllare modelli
+già aggiunti [qui](https://github.com/huggingface/transformers/pulls?q=is%3Apr+label%3A%22PR+for+Model+Addition%22+is%3Aclosed),
+per capire se richiamano il modello che vorreste aggiungere.
+
+Per cominciare, vediamo una panoramica general della libreria Transformers.
+
+## Panoramica generale su 🤗 Transformers
+
+Prima di tutto, vediamo in generale 🤗 Transformers. 🤗 Transformers é una libreria molto strutturata, quindi
+puà essere che a volte ci sia un disaccordo con alcune filosofie della libreria o scelte di design. Dalla nostra esperienza,
+tuttavia, abbiamo trovato che le scelte fondamentali di design della libreria sono cruciali per usare 🤗 Transformers efficacemente
+su larga scala, mantenendo i costi a un livello accettabile.
+
+Un buon primo punto di partenza per capire al meglio la libreria é leggere la [documentazione sulla nostra filosofia](filosofia)
+Da qui, ci sono alcune scelte sul modo di lavorare che cerchiamo di applicare a tutti i modelli:
+
+- La composizione é generalmente favorita sulla sovra-astrazione
+- Duplicare il codice non é sempre male, soprattutto se migliora notevolmente la leggibilità e accessibilità del modello
+- Tutti i files creati per il nuovo modello devono il piu possibile "compatti". Questo vuol dire che quando qualcuno leggerá il codice
+di uno specifico modello, potrá vedere solo il corrispettivo file `modeling_....py` senza avere multiple dipendenze.
+
+
+La cosa piú importante, é che consideriamo la libreria non solo un mezzo per dare un prodotto, *per esempio* dare la possibilità
+di usare BERT per inferenza, ma é anche il prodotto reale che noi vogliamo migliorare sempre più. Quindi, quando aggiungi
+un modello, non sei solo la persona che userà il modello, ma rappresenti anche tutti coloro che leggeranno,
+cercheranno di capire e modificare il tuo modello.
+
+Tenendo questi principi in mente, immergiamoci nel design generale della libreria.
+
+### Panoramica sui modelli
+
+Per aggiungere con successo un modello, é importante capire l'interazione tra il tuo modello e la sua configurazione,
+[`PreTrainedModel`], e [`PretrainedConfig`]. Per dare un esempio, chiameremo il modello da aggiungere a 🤗 Transformers
+`BrandNewBert`.
+
+Diamo un'occhiata:
+
+
+
+Nel caso siate su Windows, sostituite `RUN_SLOW=1` con `SET RUN_SLOW=1`
+
+
+
+Di seguito, tutte le features che sono utili e necessarire per *brand_new_bert* devono essere testate in test separati,
+contenuti in `BrandNewBertModelTester`/ `BrandNewBertModelTest`. spesso la gente si scorda questi test, ma ricordate che sono utili per:
+
+
+- Aiuta gli utenti a capire il vostro codice meglio, richiamando l'attenzione su queste nuove features
+- Developers e contributors futuri potranno velocemente testare nuove implementazioni del modello testanto questi casi speciali.
+
+
+**9. Implementare il tokenizer**
+
+A questo punto avremo bisogno un tokenizer per *brand_new_bert*. Di solito il tokenizer é uguale ad altri modelli in 🤗 Transformers.
+
+É importante che troviate il file con il tokenizer originale e che lo carichiate in 🤗 Transformers.
+
+Per controllare che il tokenizer funzioni in modo corretto, create uno script nella repo originaria che riceva come input
+una stringa e ritorni gli `input_ids`. Piu o meno questo potrebbe essere il codice:
+
+```python
+input_str = "This is a long example input string containing special characters .$?-, numbers 2872 234 12 and words."
+model = BrandNewBertModel.load_pretrained_checkpoint("/path/to/checkpoint/")
+input_ids = model.tokenize(input_str)
+```
+
+Potrebbe richiedere un po' di tempo, ma guardate ancora alla repo originaria per trovare la funzione corretta del tokenizer.
+A volte capita di dover riscrivere il tokenizer nella repo originaria, di modo da avere come output gli `input_ids`.
+A quel punto uno script analogo é necessario in 🤗 Transformers:
+
+```python
+from transformers import BrandNewBertTokenizer
+
+input_str = "This is a long example input string containing special characters .$?-, numbers 2872 234 12 and words."
+
+tokenizer = BrandNewBertTokenizer.from_pretrained("/path/to/tokenizer/folder/")
+
+input_ids = tokenizer(input_str).input_ids
+```
+
+Una volta che `input_ids` sono uguali, bisogna aggiungere un test per il tokenizer.
+
+Il file test per tokenizer di *brand_new_brand* dovrebbe avere un paio di hard-coded test d'integrazione.
+
+
+**10. Test end-to-end**
+
+Ora che avete il tokenizer, dovrete aggiungere dei test d'integrazione per l'intero workflow in `tests/test_modeling_brand_new_bert.py` in 🤗 Transformer.
+Questi test devono mostrare che un significante campione text-to-text funzioni come ci si aspetta nell'implementazione di 🤗 Transformers.
+*Per esempio* potreste usare dei source-to-target-translation, o un sommario di un articolo, o un domanda-risposta e cosi via.
+Se nessuno dei checkpoints é stato ultra parametrizzato per task simili, allora i tests per il modello sono piu che sufficienti.
+Nello step finale dovete assicurarvi che il modello sia totalmente funzionale, e consigliamo anche di provare a testare su GPU.
+Puo succedere che ci si scordi un `.to(self.device)` ad esempio. Se non avete accesso a GPU, il team Hugging Face puo provvedere
+a testare questo aspetto per voi.
+
+**11. Aggiungere una Docstring**
+
+Siete quasi alla fine! L'ultima cosa rimasta é avere una bella docstring e una pagina doc. Il Cookiecutter dovrebbe provvedere già
+un template chiamato `docs/source/model_doc/brand_new_bert.rst`, che dovrete compilare. La prima cosa che un utente farà
+per usare il vostro modello sarà dare una bella lettura al doc. Quindi proponete una documentazione chiara e concisa. É molto
+utile per la community avere anche delle *Tips* per mostrare come il modello puo' essere usato. Non esitate a chiedere a Hugging Face
+riguardo alle docstirng.
+
+Quindi, assicuratevi che la docstring sia stata aggiunta a `src/transformers/models/brand_new_bert/modeling_brand_new_bert.py`.
+Assicuratevi che la docstring sia corretta e che includa tutti i necessari input e output. Abbiamo una guida dettagliata per
+scrivere la documentazione e docstring.
+
+
+**Rifattorizzare il codice**
+
+Perfetto! Ora che abbiamo tutto per *brand_new_bert* controllate che lo stile del codice sia ok:
+
+```bash
+make style
+```
+
+E che il codice passi i quality check:
+
+```bash
+make quality
+```
+
+A volte capita che manchino delle informazioninella docstring o alcuni nomi sbagliati, questo farà fallire i tests sopra.
+Ripetiamo: chiedete pure a Hugging Face, saremo lieti di aiutarvi.
+
+Per ultimo, fare del refactoring del codice una volta che é stato creato.
+
+Avete finito con il codice, congratulazioni! 🎉 Siete fantasticiiiiiii! 😎
+
+**12. Caricare il modello sul model hub**
+
+In questa ultima parte dovrete convertire e caricare il modello, con tutti i checkpoints, nel model hub e aggiungere una
+model card per ogni checkpoint caricato. Leggete la nostra guida [Model sharing and uploading Page](model_sharing) per
+avere familiarità con l'hub. Di solito in questa parte lavorate a fianco di Hugging face per decidere un nome che sia ok
+per ogni checkpoint, per ottenere i permessi necessari per caricare il modello nell'organizzazione dell'autore di *brand_new_bert*.
+Il metodo `push_to_hub`, presente in tutti i modelli `transformers`, é una maniera rapida e indolore per caricare il vostro checkpoint sull'hub:
+
+```python
+brand_new_bert.push_to_hub(
+ repo_path_or_name="brand_new_bert",
+ # Uncomment the following line to push to an organization
+ # organization="",
+ commit_message="Add model",
+ use_temp_dir=True,
+)
+```
+
+Vale la pena spendere un po' di tempo per creare una model card ad-hoc per ogni checkpoint. Le model cards dovrebbero
+suggerire le caratteristiche specifiche del checkpoint, *per esempio* su che dataset il checkpoint é stato pretrained o fine-tuned.
+O che su che genere di task il modello lavoro? E anche buona pratica includere del codice su come usare il modello correttamente.
+
+
+**13. (Opzionale) Aggiungere un notebook**
+
+É molto utile aggiungere un notebook, che dimostri in dettaglio come *brand_new_bert* si utilizzi per fare inferenza e/o
+fine-tuned su specifiche task. Non é una cosa obbligatoria da avere nella vostra PR, ma é molto utile per la community.
+
+**14. Sottomettere la PR**
+
+L'ultimissimo step! Ovvero il merge della PR nel main. Di solito il team Hugging face a questo punto vi avrà gia aiutato,
+ma é ok prendere un po' di tempo per pulire la descirzione e commenti nel codice.
+
+
+### Condividete il vostro lavoro!!
+
+É ora tempo di prendere un po' di credito dalla communità per il vostro lavoro! Caricare e implementare un nuovo modello
+é un grandissimo contributo per Transformers e l'intera community NLP. Il codice e la conversione dei modelli pre-trained sara
+sicuramente utilizzato da centinaia o migliaia di sviluppatori e ricercatori. Siate fieri e orgogliosi di condividere il vostro
+traguardo con l'intera community :)
+
+** Avete create un altro modello che é super facile da usare per tutti quanti nella community! 🤯**
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/add_new_pipeline.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/add_new_pipeline.md
new file mode 100644
index 0000000000000000000000000000000000000000..fcc4da1899a2b1d7ff44e9b0075fded4e271f390
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/add_new_pipeline.md
@@ -0,0 +1,246 @@
+
+
+# Come creare una pipeline personalizzata?
+
+In questa guida, scopriremo come creare una pipeline personalizzata e condividerla sull' [Hub](https://hf.co/models) o aggiungerla nella libreria
+Transformers.
+
+Innanzitutto, è necessario decidere gli input grezzi che la pipeline sarà in grado di accettare. Possono essere strings, raw bytes,
+dictionaries o qualsiasi cosa sia l'input desiderato più probabile. Cerca di mantenere questi input il più possibile in Python
+in quanto facilita la compatibilità (anche con altri linguaggi tramite JSON). Questi saranno gli `inputs` della
+pipeline (`preprocess`).
+
+Poi definire gli `outputs`. Stessa strategia degli `inputs`. Più è seplice e meglio è. Questi saranno gli output del metodo
+`postprocess`.
+
+Si parte ereditando la classe base `Pipeline`. con i 4 metodi che bisogna implementare `preprocess`,
+`_forward`, `postprocess` e `_sanitize_parameters`.
+
+
+```python
+from transformers import Pipeline
+
+
+class MyPipeline(Pipeline):
+ def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "maybe_arg" in kwargs:
+ preprocess_kwargs["maybe_arg"] = kwargs["maybe_arg"]
+ return preprocess_kwargs, {}, {}
+
+ def preprocess(self, inputs, maybe_arg=2):
+ model_input = Tensor(inputs["input_ids"])
+ return {"model_input": model_input}
+
+ def _forward(self, model_inputs):
+ # model_inputs == {"model_input": model_input}
+ outputs = self.model(**model_inputs)
+ # Maybe {"logits": Tensor(...)}
+ return outputs
+
+ def postprocess(self, model_outputs):
+ best_class = model_outputs["logits"].softmax(-1)
+ return best_class
+```
+
+La struttura di questa suddivisione consiste nel supportare in modo relativamente continuo CPU/GPU, supportando allo stesso tempo l'esecuzione di
+pre/postelaborazione sulla CPU su thread diversi.
+
+`preprocess` prenderà gli input originariamente definiti e li trasformerà in qualcosa di alimentabile dal modello. Potrebbe
+contenere più informazioni e di solito è un `Dict`.
+
+`_forward` è il dettaglio dell'implementazione e non è destinato a essere chiamato direttamente. `forward` è il metodo preferito per assicurarsi che tutto funzioni correttamente perchè contiene delle slavaguardie. Se qualcosa è
+è collegato a un modello reale, appartiene al metodo `_forward`, tutto il resto è nel preprocess/postprocess.
+
+`postprocess` prende l'otput di `_forward` e lo trasforma nell'output finale che era stato deciso in precedenza.
+
+`_sanitize_parameters` esiste per consentire agli utenti di passare i parametri ogni volta che desiderano sia a inizialization time `pipeline(...., maybe_arg=4)` che al call time `pipe = pipeline(...); output = pipe(...., maybe_arg=4)`.
+
+`_sanitize_parameters` ritorna 3 dicts di kwargs che vengono passati direttamente a `preprocess`,
+`_forward` e `postprocess`. Non riempire nulla se il chiamante non ha chiamato con alcun parametro aggiuntivo. Questo
+consente di mantenere gli argomenti predefiniti nella definizione della funzione, che è sempre più "naturale".
+
+Un esempio classico potrebbe essere l'argomento `top_k` nel post processing dei classification tasks.
+
+```python
+>>> pipe = pipeline("my-new-task")
+>>> pipe("This is a test")
+[{"label": "1-star", "score": 0.8}, {"label": "2-star", "score": 0.1}, {"label": "3-star", "score": 0.05}
+{"label": "4-star", "score": 0.025}, {"label": "5-star", "score": 0.025}]
+
+>>> pipe("This is a test", top_k=2)
+[{"label": "1-star", "score": 0.8}, {"label": "2-star", "score": 0.1}]
+```
+
+In order to achieve that, we'll update our `postprocess` method with a default parameter to `5`. and edit
+`_sanitize_parameters` to allow this new parameter.
+
+
+```python
+def postprocess(self, model_outputs, top_k=5):
+ best_class = model_outputs["logits"].softmax(-1)
+ # Add logic to handle top_k
+ return best_class
+
+
+def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "maybe_arg" in kwargs:
+ preprocess_kwargs["maybe_arg"] = kwargs["maybe_arg"]
+
+ postprocess_kwargs = {}
+ if "top_k" in kwargs:
+ postprocess_kwargs["top_k"] = kwargs["top_k"]
+ return preprocess_kwargs, {}, postprocess_kwargs
+```
+
+Cercare di mantenere gli input/output molto semplici e idealmente serializzabili in JSON, in quanto ciò rende l'uso della pipeline molto facile
+senza richiedere agli utenti di comprendere nuovi tipi di oggetti. È anche relativamente comune supportare molti tipi di argomenti
+per facilitarne l'uso (ad esempio file audio, possono essere nomi di file, URL o byte puri).
+
+## Aggiungilo alla lista dei tasks supportati
+
+Per registrar il tuo `new-task` alla lista dei tasks supportati, devi aggiungerlo al `PIPELINE_REGISTRY`:
+
+```python
+from transformers.pipelines import PIPELINE_REGISTRY
+
+PIPELINE_REGISTRY.register_pipeline(
+ "new-task",
+ pipeline_class=MyPipeline,
+ pt_model=AutoModelForSequenceClassification,
+)
+```
+
+Puoi specificare il modello di default che desideri, in questo caso dovrebbe essere accompagnato da una revisione specifica (che può essere il nome di un branch o l'hash di un commit, in questo caso abbiamo preso `"abcdef"`) e anche dal type:
+
+```python
+PIPELINE_REGISTRY.register_pipeline(
+ "new-task",
+ pipeline_class=MyPipeline,
+ pt_model=AutoModelForSequenceClassification,
+ default={"pt": ("user/awesome_model", "abcdef")},
+ type="text", # current support type: text, audio, image, multimodal
+)
+```
+
+## Condividi la tua pipeline sull'Hub
+
+Per condividere la tua pipeline personalizzata sull'Hub, devi solo salvare il codice della tua sottoclasse `Pipeline` in un file
+python. Per esempio, supponiamo di voler utilizzare una pipeline personalizzata per la classificazione delle coppie di frasi come la seguente:
+
+```py
+import numpy as np
+
+from transformers import Pipeline
+
+
+def softmax(outputs):
+ maxes = np.max(outputs, axis=-1, keepdims=True)
+ shifted_exp = np.exp(outputs - maxes)
+ return shifted_exp / shifted_exp.sum(axis=-1, keepdims=True)
+
+
+class PairClassificationPipeline(Pipeline):
+ def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "second_text" in kwargs:
+ preprocess_kwargs["second_text"] = kwargs["second_text"]
+ return preprocess_kwargs, {}, {}
+
+ def preprocess(self, text, second_text=None):
+ return self.tokenizer(text, text_pair=second_text, return_tensors=self.framework)
+
+ def _forward(self, model_inputs):
+ return self.model(**model_inputs)
+
+ def postprocess(self, model_outputs):
+ logits = model_outputs.logits[0].numpy()
+ probabilities = softmax(logits)
+
+ best_class = np.argmax(probabilities)
+ label = self.model.config.id2label[best_class]
+ score = probabilities[best_class].item()
+ logits = logits.tolist()
+ return {"label": label, "score": score, "logits": logits}
+```
+
+L'implementazione è agnostica al framework, e lavorerà sia con modelli PyTorch che con TensorFlow. Se l'abbiamo salvato in un file chiamato `pair_classification.py`, può essere successivamente importato e registrato in questo modo:
+
+```py
+from pair_classification import PairClassificationPipeline
+from transformers.pipelines import PIPELINE_REGISTRY
+from transformers import AutoModelForSequenceClassification, TFAutoModelForSequenceClassification
+
+PIPELINE_REGISTRY.register_pipeline(
+ "pair-classification",
+ pipeline_class=PairClassificationPipeline,
+ pt_model=AutoModelForSequenceClassification,
+ tf_model=TFAutoModelForSequenceClassification,
+)
+```
+
+Una volta fatto, possiamo usarla con un modello pretrained. L'istanza `sgugger/finetuned-bert-mrpc` è stata
+fine-tuned sul dataset MRPC, che classifica le coppie di frasi come parafrasi o no.
+
+```py
+from transformers import pipeline
+
+classifier = pipeline("pair-classification", model="sgugger/finetuned-bert-mrpc")
+```
+
+Successivamente possiamo condividerlo sull'Hub usando il metodo `push_to_hub`
+
+```py
+classifier.push_to_hub("test-dynamic-pipeline")
+```
+
+Questo codice copierà il file dove è stato definitp `PairClassificationPipeline` all'interno della cartella `"test-dynamic-pipeline"`,
+insieme al salvataggio del modello e del tokenizer della pipeline, prima di pushare il tutto nel repository
+`{your_username}/test-dynamic-pipeline`. Dopodiché chiunque potrà utilizzarlo, purché fornisca l'opzione
+`trust_remote_code=True`:
+
+```py
+from transformers import pipeline
+
+classifier = pipeline(model="{your_username}/test-dynamic-pipeline", trust_remote_code=True)
+```
+
+## Aggiungere la pipeline a Transformers
+
+Se vuoi contribuire con la tua pipeline a Transformers, dovrai aggiungere un modulo nel sottomodulo `pipelines`
+con il codice della tua pipeline, quindi aggiungilo all'elenco dei tasks definiti in `pipelines/__init__.py`.
+
+Poi hai bisogno di aggiungere i test. Crea un nuovo file `tests/test_pipelines_MY_PIPELINE.py` con esempi ed altri test.
+
+La funzione `run_pipeline_test` sarà molto generica e su piccoli modelli casuali su ogni possibile
+architettura, come definito da `model_mapping` e `tf_model_mapping`.
+
+Questo è molto importante per testare la compatibilità futura, nel senso che se qualcuno aggiunge un nuovo modello di
+`XXXForQuestionAnswering` allora il test della pipeline tenterà di essere eseguito su di esso. Poiché i modelli sono casuali, è
+è impossibile controllare i valori effettivi, per questo esiste un aiuto `ANY` che tenterà solamente di far corrispondere l'output della pipeline TYPE.
+
+Hai anche *bisogno* di implementare 2 (idealmente 4) test.
+
+- `test_small_model_pt` : Definire 1 piccolo modello per questa pipeline (non importa se i risultati non hanno senso)
+ e testare i risultati della pipeline. I risultati dovrebbero essere gli stessi di `test_small_model_tf`.
+- `test_small_model_tf` : Definire 1 piccolo modello per questa pipeline (non importa se i risultati non hanno senso)
+ e testare i risultati della pipeline. I risultati dovrebbero essere gli stessi di `test_small_model_pt`.
+- `test_large_model_pt` (`optional`): Testare la pipeline su una pipeline reale in cui i risultati dovrebbero avere
+ senso. Questi test sono lenti e dovrebbero essere contrassegnati come tali. In questo caso l'obiettivo è mostrare la pipeline e assicurarsi che non ci siano derive nelle versioni future
+- `test_large_model_tf` (`optional`): Testare la pipeline su una pipeline reale in cui i risultati dovrebbero avere
+ senso. Questi test sono lenti e dovrebbero essere contrassegnati come tali. In questo caso l'obiettivo è mostrare la pipeline e assicurarsi
+ che non ci siano derive nelle versioni future
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/autoclass_tutorial.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/autoclass_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..edb96528e705eacebdf5281e35f7ce620bd3d8bd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/autoclass_tutorial.md
@@ -0,0 +1,123 @@
+
+
+# Carica istanze pre-allenate con AutoClass
+
+Con così tante architetture Transformer differenti, può essere sfidante crearne una per il tuo checkpoint. Come parte della filosofia centrale di 🤗 Transformers per rendere la libreria facile, semplice e flessibile da utilizzare, una `AutoClass` inferisce e carica automaticamente l'architettura corretta da un dato checkpoint. Il metodo `from_pretrained` ti permette di caricare velocemente un modello pre-allenato per qualsiasi architettura, così non devi utilizzare tempo e risorse per allenare un modello da zero. Produrre questo codice agnostico ai checkpoint significa che se il tuo codice funziona per un checkpoint, funzionerà anche per un altro checkpoint, purché sia stato allenato per un compito simile, anche se l'architettura è differente.
+
+
+
+Ricorda, con architettura ci si riferisce allo scheletro del modello e con checkpoint ai pesi di una determinata architettura. Per esempio, [BERT](https://huggingface.co/google-bert/bert-base-uncased) è un'architettura, mentre `google-bert/bert-base-uncased` è un checkpoint. Modello è un termine generale che può significare sia architettura che checkpoint.
+
+
+
+In questo tutorial, imparerai a:
+
+* Caricare un tokenizer pre-allenato.
+* Caricare un estrattore di caratteristiche (feature extractor, in inglese) pre-allenato.
+* Caricare un processore pre-allenato.
+* Caricare un modello pre-allenato.
+
+## AutoTokenizer
+
+Quasi tutti i compiti di NLP iniziano con un tokenizer. Un tokenizer converte il tuo input in un formato che possa essere elaborato dal modello.
+
+Carica un tokenizer con [`AutoTokenizer.from_pretrained`]:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("FacebookAI/xlm-roberta-base")
+```
+
+Poi tokenizza il tuo input come mostrato in seguito:
+
+```py
+>>> sequenza = "In un buco nel terreno viveva uno Hobbit."
+>>> print(tokenizer(sequenza))
+{'input_ids': [0, 360, 51, 373, 587, 1718, 54644, 22597, 330, 3269, 2291, 22155, 18, 5, 2],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+## AutoFeatureExtractor
+
+Per compiti inerenti a audio e video, un feature extractor processa il segnale audio o l'immagine nel formato di input corretto.
+
+Carica un feature extractor con [`AutoFeatureExtractor.from_pretrained`]:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained(
+... "ehcalabres/wav2vec2-lg-xlsr-en-speech-emotion-recognition"
+... )
+```
+
+## AutoProcessor
+
+Compiti multimodali richiedono un processore che combini i due tipi di strumenti di elaborazione. Per esempio, il modello [LayoutLMV2](model_doc/layoutlmv2) richiede un feature extractor per gestire le immagine e un tokenizer per gestire il testo; un processore li combina entrambi.
+
+Carica un processore con [`AutoProcessor.from_pretrained`]:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("microsoft/layoutlmv2-base-uncased")
+```
+
+## AutoModel
+
+
+
+Infine, le classi `AutoModelFor` ti permettono di caricare un modello pre-allenato per un determinato compito (guarda [qui](model_doc/auto) per una lista completa di compiti presenti). Per esempio, carica un modello per la classificazione di sequenze con [`AutoModelForSequenceClassification.from_pretrained`]:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Semplicemente utilizza lo stesso checkpoint per caricare un'architettura per un task differente:
+
+```py
+>>> from transformers import AutoModelForTokenClassification
+
+>>> model = AutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Generalmente, raccomandiamo di utilizzare la classe `AutoTokenizer` e la classe `AutoModelFor` per caricare istanze pre-allenate dei modelli. Questo ti assicurerà di aver caricato la corretta architettura ogni volta. Nel prossimo [tutorial](preprocessing), imparerai come utilizzare il tokenizer, il feature extractor e il processore per elaborare un dataset per il fine-tuning.
+
+
+
+Infine, le classi `TFAutoModelFor` ti permettono di caricare un modello pre-allenato per un determinato compito (guarda [qui](model_doc/auto) per una lista completa di compiti presenti). Per esempio, carica un modello per la classificazione di sequenze con [`TFAutoModelForSequenceClassification.from_pretrained`]:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Semplicemente utilizza lo stesso checkpoint per caricare un'architettura per un task differente:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Generalmente, raccomandiamo di utilizzare la classe `AutoTokenizer` e la classe `TFAutoModelFor` per caricare istanze pre-allenate dei modelli. Questo ti assicurerà di aver caricato la corretta architettura ogni volta. Nel prossimo [tutorial](preprocessing), imparerai come utilizzare il tokenizer, il feature extractor e il processore per elaborare un dataset per il fine-tuning.
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/big_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/big_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..6a5c346dec890fb29b2f91a22dfe609229d8b1b8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/big_models.md
@@ -0,0 +1,123 @@
+
+
+# Istanziare un big model
+
+Quando vuoi utilizzare un modello preaddestrato (pretrained) molto grande, una sfida è minimizzare l'uso della RAM. Il workflow classico
+in PyTorch è:
+
+1. Crea il tuo modello con pesi casuali (random weights).
+2. Carica i tuoi pesi preaddestrati.
+3. Inserisci i pesi preaddestrati nel tuo modello casuale.
+
+I passi 1 e 2 una versione completa del modello in memoria, in molti casi non è un problema, ma se il modello inizia a pesare diversi GigaBytes, queste due copie possono sturare la nostra RAM. Ancora peggio, se stai usando `torch.distributed` per seguire l'addestramento (training) in distribuito, ogni processo caricherà il modello preaddestrato e memorizzerà queste due copie nella RAM.
+
+
+
+Nota che il modello creato casualmente è inizializzato con tensori "vuoti", che occupano spazio in memoria ma senza riempirlo (quindi i valori casuali sono quelli che si trovavano in questa porzione di memoria in un determinato momento). L'inizializzazione casuale che segue la distribuzione appropriata per il tipo di modello/parametri istanziato (come la distribuzione normale per le istanze) è eseguito solo dopo il passaggio 3 sui pesi non inizializzati, per essere più rapido possibile!
+
+
+
+In questa guida, esploreremo le soluzioni che Transformers offre per affrontare questo problema. C'è da tenere in conto che questa è un'area in cui si sta attualmente sviluppando, quindi le API spiegate qui possono variare velocemente in futuro.
+
+## Checkpoints condivisi
+
+Dalla versione 4.18.0, i checkpoints dei modelli che occupano più di 10GB di spazio vengono automaticamente frammentati in più parti. Per quanto riguarda la possibilità di avere un unico checkpoint quando si utilizza `model.save_pretrained(save_dir)`, si hanno diversi checkpoint parziali (ognuno con dimensione < 10GB) e un indice che mappa i nomi dei parametri ai file in cui sono memorizzati.
+
+Puoi controllare la dimensione massima dopo la frammentazione con il parametro `max_shard_size`, nel prossimo esempio, useremo modelli di dimensioni normali con frammenti di piccoli dimensioni: prendiamo un modello BERT classico.
+
+```py
+from transformers import AutoModel
+
+model = AutoModel.from_pretrained("google-bert/bert-base-cased")
+```
+
+Se tu salvi usando [`~PreTrainedModel.save_pretrained`], avrai una nuova cartella con due file: il config del modello e i suoi pesi:
+
+```py
+>>> import os
+>>> import tempfile
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir)
+... print(sorted(os.listdir(tmp_dir)))
+['config.json', 'pytorch_model.bin']
+```
+
+Adesso usiamo una dimensione massima di frammentazione di 200MB:
+
+```py
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... print(sorted(os.listdir(tmp_dir)))
+['config.json', 'pytorch_model-00001-of-00003.bin', 'pytorch_model-00002-of-00003.bin', 'pytorch_model-00003-of-00003.bin', 'pytorch_model.bin.index.json']
+```
+
+In aggiunta alla configurazione del modello, vediamo tre differenti file dei pesi, e un file `index.json` che è il nostro indice. Un checkpoint può essere ricaricato totalmente usando il metodo [`~PreTrainedModel.from_pretrained`]:
+
+```py
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... new_model = AutoModel.from_pretrained(tmp_dir)
+```
+
+Il vantaggio principale di applicare questo metodo per modelli grandi è che durante il passo 2 del workflow illustrato in precedenza, ogni frammento del checkpoint viene caricato dopo il precedente, limitando l'utilizzo della RAM alla dimensione del modello più la dimensione del frammento più grande.
+
+Dietro le quinte, il file indice è utilizzato per determinare quali chiavi sono nel checkpoint, e dove i corrispondenti pesi sono memorizzati. Possiamo caricare l'indice come un qualsiasi json e ottenere un dizionario:
+
+```py
+>>> import json
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... with open(os.path.join(tmp_dir, "pytorch_model.bin.index.json"), "r") as f:
+... index = json.load(f)
+
+>>> print(index.keys())
+dict_keys(['metadata', 'weight_map'])
+```
+
+I metadati consistono solo nella dimensione totale del modello per ora. Abbiamo in programma di aggiungere altre informazioni in futuro:
+
+```py
+>>> index["metadata"]
+{'total_size': 433245184}
+```
+
+La mappa dei pesi è la parte principale di questo indice, che mappa ogni nome dei parametri (si trova solitamente nei modelli PyTorch come `state_dict`) al file in cui è memorizzato:
+
+```py
+>>> index["weight_map"]
+{'embeddings.LayerNorm.bias': 'pytorch_model-00001-of-00003.bin',
+ 'embeddings.LayerNorm.weight': 'pytorch_model-00001-of-00003.bin',
+ ...
+```
+
+Se vuoi caricare direttamente un checkpoint frammentato in un modello senza usare [`~PreTrainedModel.from_pretrained`] (come si farebbe con `model.load_state_dict()` per un checkpoint completo) devi usare [`~modeling_utils.load_sharded_checkpoint`]:
+
+```py
+>>> from transformers.modeling_utils import load_sharded_checkpoint
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... load_sharded_checkpoint(model, tmp_dir)
+```
+
+## Caricamento low memory
+
+Frammentare i checkpoint l'utilizzo di memoria al passo 2 del workflow citato in precedenza, ma per utilizzare questo modello in un ambiente con poca memoria, consigliamo di utilizzare i nostri strumenti basati sulla libreria Accelerate.
+
+Per ulteriori informazioni, leggere la seguente guida: [Large model loading using Accelerate](./main_classes/model#large-model-loading)
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/community.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/community.md
new file mode 100644
index 0000000000000000000000000000000000000000..92f6698a9a89bb8243ea84e3ab5698d2e8374f90
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/community.md
@@ -0,0 +1,68 @@
+
+
+# Comunità
+
+Questa pagina raggruppa le risorse sviluppate dalla comunità riguardo 🤗 Transformers.
+
+## Risorse della comunità:
+
+| Risorsa | Descrizione | Autore |
+|:----------|:-------------|------:|
+| [Glossario delle Flashcards di Transformers](https://www.darigovresearch.com/huggingface-transformers-glossary-flashcards) | Un insieme di flashcards basate sul [glossario della documentazione di Transformers](glossary), creato in un formato tale da permettere un facile apprendimento e revisione usando [Anki](https://apps.ankiweb.net/), un'applicazione open-source e multi-piattaforma, specificatamente progettata per ricordare informazioni nel lungo termine. Guarda questo [video introduttivo su come usare le flashcards](https://www.youtube.com/watch?v=Dji_h7PILrw). | [Darigov Research](https://www.darigovresearch.com/) |
+
+## Notebook della comunità:
+
+| Notebook | Descrizione | Autore | |
+|:----------|:-------------|:-------------|------:|
+| [Fine-tuning di un Transformer pre-addestrato, al fine di generare testi di canzoni](https://github.com/AlekseyKorshuk/huggingartists) | Come generare testi di canzoni nello stile del vostro artista preferito attraverso il fine-tuning di un modello GPT-2. | [Aleksey Korshuk](https://github.com/AlekseyKorshuk) | [](https://colab.research.google.com/github/AlekseyKorshuk/huggingartists/blob/master/huggingartists-demo.ipynb) |
+| [Addestramento di T5 in Tensorflow 2](https://github.com/snapthat/TF-T5-text-to-text) | Come addestrare T5 per qualsiasi attività usando Tensorflow 2. Questo notebook mostra come risolvere l'attività di "Question Answering" usando Tensorflow 2 e SQUAD. | [Muhammad Harris](https://github.com/HarrisDePerceptron) |[](https://colab.research.google.com/github/snapthat/TF-T5-text-to-text/blob/master/snapthatT5/notebooks/TF-T5-Datasets%20Training.ipynb) |
+| [Addestramento di T5 con TPU](https://github.com/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb) | Come addestrare T5 su SQUAD con Transformers e NLP. | [Suraj Patil](https://github.com/patil-suraj) |[](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb#scrollTo=QLGiFCDqvuil) |
+| [Fine-tuning di T5 per la classificazione e scelta multipla](https://github.com/patil-suraj/exploring-T5/blob/master/t5_fine_tuning.ipynb) | Come effettuare il fine-tuning di T5 per le attività di classificazione a scelta multipla - usando un formato testo-a-testo - con PyTorch Lightning. | [Suraj Patil](https://github.com/patil-suraj) | [](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/t5_fine_tuning.ipynb) |
+| [Fine-tuning di DialoGPT su nuovi dataset e lingue](https://github.com/ncoop57/i-am-a-nerd/blob/master/_notebooks/2020-05-12-chatbot-part-1.ipynb) | Come effettuare il fine-tuning di un modello DialoGPT su un nuovo dataset per chatbots conversazionali open-dialog. | [Nathan Cooper](https://github.com/ncoop57) | [](https://colab.research.google.com/github/ncoop57/i-am-a-nerd/blob/master/_notebooks/2020-05-12-chatbot-part-1.ipynb) |
+| [Modellamento di una lunga sequenza con Reformer](https://github.com/patrickvonplaten/notebooks/blob/master/PyTorch_Reformer.ipynb) | Come addestrare su sequenze di lunghezza fino a 500 mila token con Reformer. | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/PyTorch_Reformer.ipynb) |
+| [Fine-tuning di BART per riassumere testi](https://github.com/ohmeow/ohmeow_website/blob/master/_notebooks/2020-05-23-text-generation-with-blurr.ipynb) | Come effettuare il fine-tuning di BART per riassumere testi con fastai usando blurr. | [Wayde Gilliam](https://ohmeow.com/) | [](https://colab.research.google.com/github/ohmeow/ohmeow_website/blob/master/_notebooks/2020-05-23-text-generation-with-blurr.ipynb) |
+| [Fine-tuning di un Transformer pre-addestrato su tweet](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb) | Come generare tweet nello stile del tuo account Twitter preferito attraverso il fine-tuning di un modello GPT-2. | [Boris Dayma](https://github.com/borisdayma) | [](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb) |
+| [Ottimizzazione di modelli 🤗 Hugging Face con Weights & Biases](https://colab.research.google.com/github/wandb/examples/blob/master/colabs/huggingface/Optimize_Hugging_Face_models_with_Weights_%26_Biases.ipynb) | Un tutorial completo che mostra l'integrazione di W&B con Hugging Face. | [Boris Dayma](https://github.com/borisdayma) | [](https://colab.research.google.com/github/wandb/examples/blob/master/colabs/huggingface/Optimize_Hugging_Face_models_with_Weights_%26_Biases.ipynb) |
+| [Longformer pre-addestrato](https://github.com/allenai/longformer/blob/master/scripts/convert_model_to_long.ipynb) | Come costruire una versione "long" degli esistenti modelli pre-addestrati. | [Iz Beltagy](https://beltagy.net) | [](https://colab.research.google.com/github/allenai/longformer/blob/master/scripts/convert_model_to_long.ipynb) |
+| [Fine-tuning di Longformer per QA](https://github.com/patil-suraj/Notebooks/blob/master/longformer_qa_training.ipynb) | Come effettuare il fine-tuning di un modello longformer per un task di QA.| [Suraj Patil](https://github.com/patil-suraj) | [](https://colab.research.google.com/github/patil-suraj/Notebooks/blob/master/longformer_qa_training.ipynb) |
+| [Valutazione di modelli con 🤗NLP](https://github.com/patrickvonplaten/notebooks/blob/master/How_to_evaluate_Longformer_on_TriviaQA_using_NLP.ipynb) | Come valutare longformer su TriviaQA con `NLP`. | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/drive/1m7eTGlPmLRgoPkkA7rkhQdZ9ydpmsdLE?usp=sharing) |
+| [Fine-tuning di T5 per Sentiment Span Extraction](https://github.com/enzoampil/t5-intro/blob/master/t5_qa_training_pytorch_span_extraction.ipynb) | Come effettuare il fine-tuning di T5 per la sentiment span extraction - usando un formato testo-a-testo - con PyTorch Lightning. | [Lorenzo Ampil](https://github.com/enzoampil) | [](https://colab.research.google.com/github/enzoampil/t5-intro/blob/master/t5_qa_training_pytorch_span_extraction.ipynb) |
+| [Fine-tuning di DistilBert per la classificazione multi-classe](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_multiclass_classification.ipynb) | Come effettuare il fine-tuning di DistilBert per la classificazione multi-classe con PyTorch. | [Abhishek Kumar Mishra](https://github.com/abhimishra91) | [](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_multiclass_classification.ipynb)|
+|[Fine-tuning di BERT per la classificazione multi-etichetta](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_multi_label_classification.ipynb)|Come effettuare il fine-tuning di BERT per la classificazione multi-etichetta con PyTorch. |[Abhishek Kumar Mishra](https://github.com/abhimishra91) |[](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_multi_label_classification.ipynb)|
+|[Accelerazione del fine-tuning con il Dynamic Padding / Bucketing](https://github.com/ELS-RD/transformers-notebook/blob/master/Divide_Hugging_Face_Transformers_training_time_by_2_or_more.ipynb)| Come velocizzare il fine-tuning di un fattore 2X usando il dynamic padding / bucketing. |[Michael Benesty](https://github.com/pommedeterresautee) |[](https://colab.research.google.com/drive/1CBfRU1zbfu7-ijiOqAAQUA-RJaxfcJoO?usp=sharing)|
+|[Pre-addestramento di Reformer per Masked Language Modeling](https://github.com/patrickvonplaten/notebooks/blob/master/Reformer_For_Masked_LM.ipynb)| Come addestrare un modello Reformer usando livelli di self-attention bi-direzionali.| [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/drive/1tzzh0i8PgDQGV3SMFUGxM7_gGae3K-uW?usp=sharing)|
+|[Espansione e fine-tuning di Sci-BERT](https://github.com/lordtt13/word-embeddings/blob/master/COVID-19%20Research%20Data/COVID-SciBERT.ipynb)| Come incrementare il vocabolario di un modello SciBERT - pre-addestrato da AllenAI sul dataset CORD - e crearne una pipeline. | [Tanmay Thakur](https://github.com/lordtt13) | [](https://colab.research.google.com/drive/1rqAR40goxbAfez1xvF3hBJphSCsvXmh8)|
+|[Fine-tuning di BlenderBotSmall per riassumere testi usando Trainer API](https://github.com/lordtt13/transformers-experiments/blob/master/Custom%20Tasks/fine-tune-blenderbot_small-for-summarization.ipynb)| Come effettuare il fine-tuning di BlenderBotSmall per riassumere testi su un dataset personalizzato, usando Trainer API. | [Tanmay Thakur](https://github.com/lordtt13) | [](https://colab.research.google.com/drive/19Wmupuls7mykSGyRN_Qo6lPQhgp56ymq?usp=sharing)|
+|[Fine-tuning di Electra e interpretazione con Integrated Gradients](https://github.com/elsanns/xai-nlp-notebooks/blob/master/electra_fine_tune_interpret_captum_ig.ipynb) | Come effettuare il fine-tuning di Electra per l'analisi dei sentimenti e intepretare le predizioni con Captum Integrated Gradients. | [Eliza Szczechla](https://elsanns.github.io) | [](https://colab.research.google.com/github/elsanns/xai-nlp-notebooks/blob/master/electra_fine_tune_interpret_captum_ig.ipynb)|
+|[Fine-tuning di un modello GPT-2 non inglese con la classe Trainer](https://github.com/philschmid/fine-tune-GPT-2/blob/master/Fine_tune_a_non_English_GPT_2_Model_with_Huggingface.ipynb) | Come effettuare il fine-tuning di un modello GPT-2 non inglese con la classe Trainer. | [Philipp Schmid](https://www.philschmid.de) | [](https://colab.research.google.com/github/philschmid/fine-tune-GPT-2/blob/master/Fine_tune_a_non_English_GPT_2_Model_with_Huggingface.ipynb)|
+|[Fine-tuning di un modello DistilBERT per la classficazione multi-etichetta](https://github.com/DhavalTaunk08/Transformers_scripts/blob/master/Transformers_multilabel_distilbert.ipynb) | Come effettuare il fine-tuning di un modello DistilBERT per l'attività di classificazione multi-etichetta. | [Dhaval Taunk](https://github.com/DhavalTaunk08) | [](https://colab.research.google.com/github/DhavalTaunk08/Transformers_scripts/blob/master/Transformers_multilabel_distilbert.ipynb)|
+|[Fine-tuning di ALBERT per la classifcazione di coppie di frasi](https://github.com/NadirEM/nlp-notebooks/blob/master/Fine_tune_ALBERT_sentence_pair_classification.ipynb) | Come effettuare il fine-tuning di un modello ALBERT - o un altro modello BERT-based - per l'attività di classificazione di coppie di frasi. | [Nadir El Manouzi](https://github.com/NadirEM) | [](https://colab.research.google.com/github/NadirEM/nlp-notebooks/blob/master/Fine_tune_ALBERT_sentence_pair_classification.ipynb)|
+|[Fine-tuning di Roberta per l'analisi di sentimenti](https://github.com/DhavalTaunk08/NLP_scripts/blob/master/sentiment_analysis_using_roberta.ipynb) | Come effettuare il fine-tuning di un modello Roberta per l'analisi di sentimenti. | [Dhaval Taunk](https://github.com/DhavalTaunk08) | [](https://colab.research.google.com/github/DhavalTaunk08/NLP_scripts/blob/master/sentiment_analysis_using_roberta.ipynb)|
+|[Valutazione di modelli che generano domande](https://github.com/flexudy-pipe/qugeev) | Quanto sono accurante le risposte alle domande generate dal tuo modello transformer seq2seq? | [Pascal Zoleko](https://github.com/zolekode) | [](https://colab.research.google.com/drive/1bpsSqCQU-iw_5nNoRm_crPq6FRuJthq_?usp=sharing)|
+|[Classificazione di testo con DistilBERT e Tensorflow](https://github.com/peterbayerle/huggingface_notebook/blob/main/distilbert_tf.ipynb) | Come effettuare il fine-tuning di DistilBERT per la classificazione di testo in TensorFlow. | [Peter Bayerle](https://github.com/peterbayerle) | [](https://colab.research.google.com/github/peterbayerle/huggingface_notebook/blob/main/distilbert_tf.ipynb)|
+|[Utilizzo di BERT per riassumere testi con un modello Encoder-Decoder su CNN/Dailymail](https://github.com/patrickvonplaten/notebooks/blob/master/BERT2BERT_for_CNN_Dailymail.ipynb) | Come avviare "a caldo" un *EncoderDecoderModel* attraverso l'utilizzo di un checkpoint *google-bert/bert-base-uncased* per riassumere testi su CNN/Dailymail. | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/BERT2BERT_for_CNN_Dailymail.ipynb)|
+|[Utilizzo di RoBERTa per riassumere testi con un modello Encoder-Decoder su BBC XSum](https://github.com/patrickvonplaten/notebooks/blob/master/RoBERTaShared_for_BBC_XSum.ipynb) | Come avviare "a caldo" un *EncoderDecoderModel* (condiviso) attraverso l'utilizzo di un checkpoint *FacebookAI/roberta-base* per riassumere testi su BBC/XSum. | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/RoBERTaShared_for_BBC_XSum.ipynb)|
+|[Fine-tuning di TAPAS su Sequential Question Answering (SQA)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) | Come effettuare il fine-tuning di un modello *TapasForQuestionAnswering* attraverso l'utilizzo di un checkpoint *tapas-base* sul dataset Sequential Question Answering (SQA). | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb)|
+|[Valutazione di TAPAS su Table Fact Checking (TabFact)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Evaluating_TAPAS_on_the_Tabfact_test_set.ipynb) | Come valutare un modello *TapasForSequenceClassification* - fine-tuned con un checkpoint *tapas-base-finetuned-tabfact* - usando una combinazione delle librerie 🤗 datasets e 🤗 transformers. | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Evaluating_TAPAS_on_the_Tabfact_test_set.ipynb)|
+|[Fine-tuning di mBART per la traduzione](https://colab.research.google.com/github/vasudevgupta7/huggingface-tutorials/blob/main/translation_training.ipynb) | Come effettuare il fine-tuning di mBART usando Seq2SeqTrainer per la traduzione da hindi a inglese.| [Vasudev Gupta](https://github.com/vasudevgupta7) | [](https://colab.research.google.com/github/vasudevgupta7/huggingface-tutorials/blob/main/translation_training.ipynb)|
+|[Fine-tuning di LayoutLM su FUNSD (un dataset per la comprensione della forma)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb) | Come effettuare il fine-tuning di un modello *LayoutLMForTokenClassification* sul dataset FUNSD per l'estrazione di informazioni da documenti scannerizzati.| [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb)|
+|[Fine-tuning di DistilGPT2 e generazione di testo](https://colab.research.google.com/github/tripathiaakash/DistilGPT2-Tutorial/blob/main/distilgpt2_fine_tuning.ipynb) | Come effettuare il fine-tuning di DistilGPT2 e generare testo. | [Aakash Tripathi](https://github.com/tripathiaakash) | [](https://colab.research.google.com/github/tripathiaakash/DistilGPT2-Tutorial/blob/main/distilgpt2_fine_tuning.ipynb)|
+|[Fine-tuning di LED fino a 8 mila token](https://github.com/patrickvonplaten/notebooks/blob/master/Fine_tune_Longformer_Encoder_Decoder_(LED)_for_Summarization_on_pubmed.ipynb) | Come effettuare il fine-tuning di LED su PubMed per riassumere "lunghi" testi. | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/Fine_tune_Longformer_Encoder_Decoder_(LED)_for_Summarization_on_pubmed.ipynb)|
+|[Valutazione di LED su Arxiv](https://github.com/patrickvonplaten/notebooks/blob/master/LED_on_Arxiv.ipynb) | Come valutare efficacemente LED sull'attività di riassumere "lunghi" testi. | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/LED_on_Arxiv.ipynb)|
+|[Fine-tuning di LayoutLM su RVL-CDIP, un dataset per la classificazione di documenti (immagini)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb) | Come effettuare il fine-tuning di un modello *LayoutLMForSequenceClassification* sul dataset RVL-CDIP per la classificazione di documenti scannerizzati. | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb)|
+|[Decodifica Wav2Vec2 CTC con variazioni di GPT2](https://github.com/voidful/huggingface_notebook/blob/main/xlsr_gpt.ipynb) | Come decodificare sequenze CTC, variate da modelli di linguaggio. | [Eric Lam](https://github.com/voidful) | [](https://colab.research.google.com/drive/1e_z5jQHYbO2YKEaUgzb1ww1WwiAyydAj?usp=sharing)
+|[Fine-tuning di BART per riassumere testi in due lingue con la classe Trainer](https://github.com/elsanns/xai-nlp-notebooks/blob/master/fine_tune_bart_summarization_two_langs.ipynb) | Come effettuare il fine-tuning di BART per riassumere testi in due lingue usando la classe Trainer. | [Eliza Szczechla](https://github.com/elsanns) | [](https://colab.research.google.com/github/elsanns/xai-nlp-notebooks/blob/master/fine_tune_bart_summarization_two_langs.ipynb)|
+|[Valutazione di Big Bird su Trivia QA](https://github.com/patrickvonplaten/notebooks/blob/master/Evaluating_Big_Bird_on_TriviaQA.ipynb) | Come valutare BigBird su question answering di "lunghi" documenti attraverso Trivia QA. | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/Evaluating_Big_Bird_on_TriviaQA.ipynb)|
+| [Creazione di sottotitoli per video usando Wav2Vec2](https://github.com/Muennighoff/ytclipcc/blob/main/wav2vec_youtube_captions.ipynb) | Come creare sottotitoli per qualsiasi video di YouTube trascrivendo l'audio con Wav2Vec. | [Niklas Muennighoff](https://github.com/Muennighoff) |[](https://colab.research.google.com/github/Muennighoff/ytclipcc/blob/main/wav2vec_youtube_captions.ipynb) |
+| [Fine-tuning di Vision Transformer su CIFAR-10 usando PyTorch Lightning](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_PyTorch_Lightning.ipynb) | Come effettuare il fine-tuning di Vision Transformer (ViT) su CIFAR-10 usando HuggingFace Transformers, Datasets e PyTorch Lightning.| [Niels Rogge](https://github.com/nielsrogge) |[](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_PyTorch_Lightning.ipynb) |
+| [Fine-tuning di Vision Transformer su CIFAR-10 usando 🤗 Trainer](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_the_%F0%9F%A4%97_Trainer.ipynb) | Come effettuare il fine-tuning di Vision Transformer (ViT) su CIFAR-10 usando HuggingFace Transformers, Datasets e 🤗 Trainer. | [Niels Rogge](https://github.com/nielsrogge) |[](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_the_%F0%9F%A4%97_Trainer.ipynb) |
+| [Valutazione di LUKE su Open Entity, un dataset di entity typing](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_open_entity.ipynb) | Come valutare un modello *LukeForEntityClassification* sul dataset Open Entity. | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_open_entity.ipynb) |
+| [Valutazione di LUKE su TACRED, un dataset per l'estrazione di relazioni](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_tacred.ipynb) | Come valutare un modello *LukeForEntityPairClassification* sul dataset TACRED. | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_tacred.ipynb) |
+| [Valutazione di LUKE su CoNLL-2003, un importante benchmark NER](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_conll_2003.ipynb) | Come valutare un modello *LukeForEntitySpanClassification* sul dataset CoNLL-2003. | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_conll_2003.ipynb) |
+| [Valutazione di BigBird-Pegasus su dataset PubMed](https://github.com/vasudevgupta7/bigbird/blob/main/notebooks/bigbird_pegasus_evaluation.ipynb) | Come valutare un modello *BigBirdPegasusForConditionalGeneration* su dataset PubMed. | [Vasudev Gupta](https://github.com/vasudevgupta7) | [](https://colab.research.google.com/github/vasudevgupta7/bigbird/blob/main/notebooks/bigbird_pegasus_evaluation.ipynb) |
+| [Classificazione di emozioni dal discorso con Wav2Vec2](https://github/m3hrdadfi/soxan/blob/main/notebooks/Emotion_recognition_in_Greek_speech_using_Wav2Vec2.ipynb) | Come utilizzare un modello pre-addestrato Wav2Vec2 per la classificazione di emozioni sul dataset MEGA. | [Mehrdad Farahani](https://github.com/m3hrdadfi) | [](https://colab.research.google.com/github/m3hrdadfi/soxan/blob/main/notebooks/Emotion_recognition_in_Greek_speech_using_Wav2Vec2.ipynb) |
+| [Rilevamento oggetti in un'immagine con DETR](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/DETR/DETR_minimal_example_(with_DetrFeatureExtractor).ipynb) | Come usare un modello addestrato *DetrForObjectDetection* per rilevare oggetti in un'immagine e visualizzare l'attention. | [Niels Rogge](https://github.com/NielsRogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/DETR/DETR_minimal_example_(with_DetrFeatureExtractor).ipynb) |
+| [Fine-tuning di DETR su un dataset personalizzato per rilevare oggetti](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/DETR/Fine_tuning_DetrForObjectDetection_on_custom_dataset_(balloon).ipynb) | Come effettuare fine-tuning di un modello *DetrForObjectDetection* su un dataset personalizzato per rilevare oggetti. | [Niels Rogge](https://github.com/NielsRogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/DETR/Fine_tuning_DetrForObjectDetection_on_custom_dataset_(balloon).ipynb) |
+| [Fine-tuning di T5 per Named Entity Recognition](https://github.com/ToluClassics/Notebooks/blob/main/T5_Ner_Finetuning.ipynb) | Come effettuare fine-tunining di *T5* per un'attività di Named Entity Recognition. | [Ogundepo Odunayo](https://github.com/ToluClassics) | [](https://colab.research.google.com/drive/1obr78FY_cBmWY5ODViCmzdY6O1KB65Vc?usp=sharing) |
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/converting_tensorflow_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/converting_tensorflow_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..8280e58cc9208b8de719b2290d12b5d454a914de
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/converting_tensorflow_models.md
@@ -0,0 +1,144 @@
+
+
+# Convertire checkpoint di Tensorflow
+
+È disponibile un'interfaccia a linea di comando per convertire gli originali checkpoint di Bert/GPT/GPT-2/Transformer-XL/XLNet/XLM
+in modelli che possono essere caricati utilizzando i metodi `from_pretrained` della libreria.
+
+
+
+A partire dalla versione 2.3.0 lo script di conversione è parte di transformers CLI (**transformers-cli**), disponibile in ogni installazione
+di transformers >=2.3.0.
+
+La seguente documentazione riflette il formato dei comandi di **transformers-cli convert**.
+
+
+
+## BERT
+
+Puoi convertire qualunque checkpoint Tensorflow di BERT (in particolare
+[i modeli pre-allenati rilasciati da Google](https://github.com/google-research/bert#pre-trained-models))
+in un file di salvataggio Pytorch utilizzando lo script
+[convert_bert_original_tf_checkpoint_to_pytorch.py](https://github.com/huggingface/transformers/tree/main/src/transformers/models/bert/convert_bert_original_tf_checkpoint_to_pytorch.py).
+
+Questo CLI prende come input un checkpoint di Tensorflow (tre files che iniziano con `bert_model.ckpt`) ed il relativo
+file di configurazione (`bert_config.json`), crea un modello Pytorch per questa configurazione, carica i pesi dal
+checkpoint di Tensorflow nel modello di Pytorch e salva il modello che ne risulta in un file di salvataggio standard di Pytorch che
+può essere importato utilizzando `from_pretrained()` (vedi l'esempio nel
+[quicktour](quicktour) , [run_glue.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-classification/run_glue.py) ).
+
+Devi soltanto lanciare questo script di conversione **una volta** per ottenere un modello Pytorch. Dopodichè, potrai tralasciare
+il checkpoint di Tensorflow (i tre files che iniziano con `bert_model.ckpt`), ma assicurati di tenere il file di configurazione
+(`bert_config.json`) ed il file di vocabolario (`vocab.txt`) in quanto queste componenti sono necessarie anche per il modello di Pytorch.
+
+Per lanciare questo specifico script di conversione avrai bisogno di un'installazione di Tensorflow e di Pytorch
+(`pip install tensorflow`). Il resto della repository richiede soltanto Pytorch.
+
+Questo è un esempio del processo di conversione per un modello `BERT-Base Uncased` pre-allenato:
+
+```bash
+export BERT_BASE_DIR=/path/to/bert/uncased_L-12_H-768_A-12
+transformers-cli convert --model_type bert \
+ --tf_checkpoint $BERT_BASE_DIR/bert_model.ckpt \
+ --config $BERT_BASE_DIR/bert_config.json \
+ --pytorch_dump_output $BERT_BASE_DIR/pytorch_model.bin
+```
+
+Puoi scaricare i modelli pre-allenati di Google per la conversione [qua](https://github.com/google-research/bert#pre-trained-models).
+
+## ALBERT
+
+Per il modello ALBERT, converti checkpoint di Tensoflow in Pytorch utilizzando lo script
+[convert_albert_original_tf_checkpoint_to_pytorch.py](https://github.com/huggingface/transformers/tree/main/src/transformers/models/albert/convert_albert_original_tf_checkpoint_to_pytorch.py).
+
+Il CLI prende come input un checkpoint di Tensorflow (tre files che iniziano con `model.ckpt-best`) e i relativi file di
+configurazione (`albert_config.json`), dopodichè crea e salva un modello Pytorch. Per lanciare questa conversione
+avrai bisogno di un'installazione di Tensorflow e di Pytorch.
+
+Ecco un esempio del procedimento di conversione di un modello `ALBERT Base` pre-allenato:
+
+```bash
+export ALBERT_BASE_DIR=/path/to/albert/albert_base
+transformers-cli convert --model_type albert \
+ --tf_checkpoint $ALBERT_BASE_DIR/model.ckpt-best \
+ --config $ALBERT_BASE_DIR/albert_config.json \
+ --pytorch_dump_output $ALBERT_BASE_DIR/pytorch_model.bin
+```
+
+Puoi scaricare i modelli pre-allenati di Google per la conversione [qui](https://github.com/google-research/albert#pre-trained-models).
+
+## OpenAI GPT
+
+Ecco un esempio del processo di conversione di un modello OpenAI GPT pre-allenato, assumendo che il tuo checkpoint di NumPy
+sia salvato nello stesso formato dei modelli pre-allenati OpenAI (vedi [qui](https://github.com/openai/finetune-transformer-lm)):
+```bash
+export OPENAI_GPT_CHECKPOINT_FOLDER_PATH=/path/to/openai/pretrained/numpy/weights
+transformers-cli convert --model_type gpt \
+ --tf_checkpoint $OPENAI_GPT_CHECKPOINT_FOLDER_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT \
+ [--config OPENAI_GPT_CONFIG] \
+ [--finetuning_task_name OPENAI_GPT_FINETUNED_TASK] \
+```
+
+## OpenAI GPT-2
+
+Ecco un esempio del processo di conversione di un modello OpenAI GPT-2 pre-allenato (vedi [qui](https://github.com/openai/gpt-2)):
+
+```bash
+export OPENAI_GPT2_CHECKPOINT_PATH=/path/to/openai-community/gpt2/pretrained/weights
+transformers-cli convert --model_type gpt2 \
+ --tf_checkpoint $OPENAI_GPT2_CHECKPOINT_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT \
+ [--config OPENAI_GPT2_CONFIG] \
+ [--finetuning_task_name OPENAI_GPT2_FINETUNED_TASK]
+```
+
+## XLNet
+
+Ecco un esempio del processo di conversione di un modello XLNet pre-allenato:
+
+```bash
+export TRANSFO_XL_CHECKPOINT_PATH=/path/to/xlnet/checkpoint
+export TRANSFO_XL_CONFIG_PATH=/path/to/xlnet/config
+transformers-cli convert --model_type xlnet \
+ --tf_checkpoint $TRANSFO_XL_CHECKPOINT_PATH \
+ --config $TRANSFO_XL_CONFIG_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT \
+ [--finetuning_task_name XLNET_FINETUNED_TASK] \
+```
+
+## XLM
+
+Ecco un esempio del processo di conversione di un modello XLM pre-allenato:
+
+```bash
+export XLM_CHECKPOINT_PATH=/path/to/xlm/checkpoint
+transformers-cli convert --model_type xlm \
+ --tf_checkpoint $XLM_CHECKPOINT_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT
+ [--config XML_CONFIG] \
+ [--finetuning_task_name XML_FINETUNED_TASK]
+```
+
+## T5
+
+Ecco un esempio del processo di conversione di un modello T5 pre-allenato:
+
+```bash
+export T5=/path/to/t5/uncased_L-12_H-768_A-12
+transformers-cli convert --model_type t5 \
+ --tf_checkpoint $T5/t5_model.ckpt \
+ --config $T5/t5_config.json \
+ --pytorch_dump_output $T5/pytorch_model.bin
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/create_a_model.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/create_a_model.md
new file mode 100644
index 0000000000000000000000000000000000000000..caacf4fadc5db6dd6f69e6a23afaeca21009a499
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/create_a_model.md
@@ -0,0 +1,361 @@
+
+
+# Crea un'architettura personalizzata
+
+Una [`AutoClass`](model_doc/auto) deduce automaticamente il modello dell'architettura e scarica la configurazione e i pesi pre-allenati. Generalmente, noi consigliamo di usare un `AutoClass` per produrre un codice indipendente dal checkpoint. Ma gli utenti che desiderano un controllo maggiore su parametri specifici del modello possono creare un modello 🤗 Transformers personalizzato da poche classi base. Questo potrebbe essere particolarmente utile per qualunque persona sia interessata nel studiare, allenare o sperimentare con un modello 🤗 Transformers. In questa guida, approfondisci la creazione di un modello personalizzato senza `AutoClass`. Impara come:
+
+- Caricare e personalizzare una configurazione del modello.
+- Creare un'architettura modello.
+- Creare un tokenizer lento e veloce per il testo.
+- Creare un estrattore di caratteristiche per attività riguardanti audio o immagini.
+- Creare un processore per attività multimodali.
+
+## Configurazione
+
+Una [configurazione](main_classes/configuration) si riferisce agli attributi specifici di un modello. Ogni configurazione del modello ha attributi diversi; per esempio, tutti i modelli npl hanno questi attributi in comune `hidden_size`, `num_attention_heads`, `num_hidden_layers` e `vocab_size`. Questi attributi specificano il numero di attention heads o strati nascosti con cui costruire un modello.
+
+Dai un'occhiata più da vicino a [DistilBERT](model_doc/distilbert) accedendo a [`DistilBertConfig`] per ispezionare i suoi attributi:
+
+```py
+>>> from transformers import DistilBertConfig
+
+>>> config = DistilBertConfig()
+>>> print(config)
+DistilBertConfig {
+ "activation": "gelu",
+ "attention_dropout": 0.1,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+[`DistilBertConfig`] mostra tutti gli attributi predefiniti usati per costruire una base [`DistilBertModel`]. Tutti gli attributi sono personalizzabili, creando uno spazio per sperimentare. Per esempio, puoi configurare un modello predefinito per:
+
+- Provare un funzione di attivazione diversa con il parametro `activation`.
+- Utilizzare tasso di drop out più elevato per le probalità di attention con il parametro `attention_dropout`.
+
+```py
+>>> my_config = DistilBertConfig(activation="relu", attention_dropout=0.4)
+>>> print(my_config)
+DistilBertConfig {
+ "activation": "relu",
+ "attention_dropout": 0.4,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+Nella funzione [`~PretrainedConfig.from_pretrained`] possono essere modificati gli attributi del modello pre-allenato:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("distilbert/distilbert-base-uncased", activation="relu", attention_dropout=0.4)
+```
+
+Quando la configurazione del modello ti soddisfa, la puoi salvare con [`~PretrainedConfig.save_pretrained`]. Il file della tua configurazione è memorizzato come file JSON nella save directory specificata:
+
+```py
+>>> my_config.save_pretrained(save_directory="./your_model_save_path")
+```
+
+Per riutilizzare la configurazione del file, caricalo con [`~PretrainedConfig.from_pretrained`]:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+```
+
+
+
+Puoi anche salvare il file di configurazione come dizionario oppure come la differenza tra gli attributi della tua configurazione personalizzata e gli attributi della configurazione predefinita! Guarda la documentazione [configuration](main_classes/configuration) per più dettagli.
+
+
+
+## Modello
+
+Il prossimo passo e di creare [modello](main_classes/models). Il modello - vagamente riferito anche come architettura - definisce cosa ogni strato deve fare e quali operazioni stanno succedendo. Attributi come `num_hidden_layers` provenienti dalla configurazione sono usati per definire l'architettura. Ogni modello condivide la classe base [`PreTrainedModel`] e alcuni metodi comuni come il ridimensionamento degli input embeddings e la soppressione delle self-attention heads . Inoltre, tutti i modelli sono la sottoclasse di [`torch.nn.Module`](https://pytorch.org/docs/stable/generated/torch.nn.Module.html), [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) o [`flax.linen.Module`](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html). Cio significa che i modelli sono compatibili con l'uso di ciascun di framework.
+
+
+
+Carica gli attributi della tua configurazione personalizzata nel modello:
+
+```py
+>>> from transformers import DistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+>>> model = DistilBertModel(my_config)
+```
+
+Questo crea modelli con valori casuali invece di pesi pre-allenati. Non sarai in grado di usare questo modello per niente di utile finché non lo alleni. L'allenamento è un processo costoso e che richiede tempo . Generalmente è meglio usare un modello pre-allenato per ottenere risultati migliori velocemente, utilizzando solo una frazione delle risorse neccesarie per l'allenamento.
+
+Crea un modello pre-allenato con [`~PreTrainedModel.from_pretrained`]:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Quando carichi pesi pre-allenati, la configurazione del modello predefinito è automaticamente caricata se il modello è fornito da 🤗 Transformers. Tuttavia, puoi ancora sostituire gli attributi - alcuni o tutti - di configurazione del modello predefinito con i tuoi se lo desideri:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+Carica gli attributi di configurazione personalizzati nel modello:
+
+```py
+>>> from transformers import TFDistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+>>> tf_model = TFDistilBertModel(my_config)
+```
+
+
+Questo crea modelli con valori casuali invece di pesi pre-allenati. Non sarai in grado di usare questo modello per niente di utile finché non lo alleni. L'allenamento è un processo costoso e che richiede tempo . Generalmente è meglio usare un modello pre-allenato per ottenere risultati migliori velocemente, utilizzando solo una frazione delle risorse neccesarie per l'allenamento.
+
+Crea un modello pre-allenoto con [`~TFPreTrainedModel.from_pretrained`]:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Quando carichi pesi pre-allenati, la configurazione del modello predefinito è automaticamente caricato se il modello è fornito da 🤗 Transformers. Tuttavia, puoi ancora sostituire gli attributi - alcuni o tutti - di configurazione del modello predefinito con i tuoi se lo desideri:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+
+
+### Model head
+
+A questo punto, hai un modello DistilBERT base i cui output sono gli *hidden states* (in italiano stati nascosti). Gli stati nascosti sono passati come input a un model head per produrre l'output finale. 🤗 Transformers fornisce un model head diverso per ogni attività fintanto che il modello supporta l'attività (i.e., non puoi usare DistilBERT per un attività sequence-to-sequence come la traduzione).
+
+
+
+Per esempio, [`DistilBertForSequenceClassification`] è un modello DistilBERT base con una testa di classificazione per sequenze. La sequenza di classificazione head è uno strato lineare sopra gli output ragruppati.
+
+```py
+>>> from transformers import DistilBertForSequenceClassification
+
+>>> model = DistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Riutilizza facilmente questo checkpoint per un'altra attività passando ad un model head differente. Per un attività di risposta alle domande, utilizzerai il model head [`DistilBertForQuestionAnswering`]. La head per compiti di question answering è simile alla classificazione di sequenza head tranne per il fatto che è uno strato lineare sopra l'output degli stati nascosti (hidden states in inglese)
+
+```py
+>>> from transformers import DistilBertForQuestionAnswering
+
+>>> model = DistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+Per esempio, [`TFDistilBertForSequenceClassification`] è un modello DistilBERT base con classificazione di sequenza head. La classificazione di sequenza head è uno strato lineare sopra gli output raggruppati.
+
+```py
+>>> from transformers import TFDistilBertForSequenceClassification
+
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Riutilizza facilmente questo checkpoint per un altra attività passando ad un modello head diverso. Per un attività di risposta alle domande, utilizzerai il model head [`TFDistilBertForQuestionAnswering`]. Il head di risposta alle domande è simile alla sequenza di classificazione head tranne per il fatto che è uno strato lineare sopra l'output degli stati nascosti (hidden states in inglese)
+
+```py
+>>> from transformers import TFDistilBertForQuestionAnswering
+
+>>> tf_model = TFDistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+## Tokenizer
+
+L'ultima classe base di cui hai bisogno prima di utilizzare un modello per i dati testuali è un [tokenizer](main_classes/tokenizer) per convertire il testo grezzo in tensori. Ci sono due tipi di tokenizer che puoi usare con 🤗 Transformers:
+
+- [`PreTrainedTokenizer`]: un'implementazione Python di un tokenizer.
+- [`PreTrainedTokenizerFast`]: un tokenizer dalla nostra libreria [🤗 Tokenizer](https://huggingface.co/docs/tokenizers/python/latest/) basata su Rust. Questo tipo di tokenizer è significativamente più veloce, specialmente durante la batch tokenization, grazie alla sua implementazione Rust. Il tokenizer veloce offre anche metodi aggiuntivi come *offset mapping* che associa i token alle loro parole o caratteri originali.
+
+Entrambi i tokenizer supportano metodi comuni come la codifica e la decodifica, l'aggiunta di nuovi token e la gestione di token speciali.
+
+
+
+Non tutti i modelli supportano un tokenizer veloce. Dai un'occhiata a questo [tabella](index#supported-frameworks) per verificare se un modello ha il supporto per tokenizer veloce.
+
+
+
+Se hai addestrato il tuo tokenizer, puoi crearne uno dal tuo file *vocabolario*:
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> my_tokenizer = DistilBertTokenizer(vocab_file="my_vocab_file.txt", do_lower_case=False, padding_side="left")
+```
+
+È importante ricordare che il vocabolario di un tokenizer personalizzato sarà diverso dal vocabolario generato dal tokenizer di un modello preallenato. È necessario utilizzare il vocabolario di un modello preallenato se si utilizza un modello preallenato, altrimenti gli input non avranno senso. Crea un tokenizer con il vocabolario di un modello preallenato con la classe [`DistilBertTokenizer`]:
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> slow_tokenizer = DistilBertTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Crea un tokenizer veloce con la classe [`DistilBertTokenizerFast`]:
+
+```py
+>>> from transformers import DistilBertTokenizerFast
+
+>>> fast_tokenizer = DistilBertTokenizerFast.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+Per l'impostazione predefinita, [`AutoTokenizer`] proverà a caricare un tokenizer veloce. Puoi disabilitare questo comportamento impostando `use_fast=False` in `from_pretrained`.
+
+
+
+## Estrattore Di Feature
+
+Un estrattore di caratteristiche (feature in inglese) elabora input audio o immagini. Eredita dalla classe [`~feature_extraction_utils.FeatureExtractionMixin`] base e può anche ereditare dalla classe [`ImageFeatureExtractionMixin`] per l'elaborazione delle caratteristiche dell'immagine o dalla classe [`SequenceFeatureExtractor`] per l'elaborazione degli input audio.
+
+A seconda che tu stia lavorando a un'attività audio o visiva, crea un estrattore di caratteristiche associato al modello che stai utilizzando. Ad esempio, crea un [`ViTFeatureExtractor`] predefinito se stai usando [ViT](model_doc/vit) per la classificazione delle immagini:
+
+```py
+>>> from transformers import ViTFeatureExtractor
+
+>>> vit_extractor = ViTFeatureExtractor()
+>>> print(vit_extractor)
+ViTFeatureExtractor {
+ "do_normalize": true,
+ "do_resize": true,
+ "feature_extractor_type": "ViTFeatureExtractor",
+ "image_mean": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": 2,
+ "size": 224
+}
+```
+
+
+
+Se non stai cercando alcuna personalizzazione, usa il metodo `from_pretrained` per caricare i parametri di default dell'estrattore di caratteristiche di un modello.
+
+
+
+Modifica uno qualsiasi dei parametri [`ViTFeatureExtractor`] per creare il tuo estrattore di caratteristiche personalizzato:
+
+```py
+>>> from transformers import ViTFeatureExtractor
+
+>>> my_vit_extractor = ViTFeatureExtractor(resample="PIL.Image.BOX", do_normalize=False, image_mean=[0.3, 0.3, 0.3])
+>>> print(my_vit_extractor)
+ViTFeatureExtractor {
+ "do_normalize": false,
+ "do_resize": true,
+ "feature_extractor_type": "ViTFeatureExtractor",
+ "image_mean": [
+ 0.3,
+ 0.3,
+ 0.3
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": "PIL.Image.BOX",
+ "size": 224
+}
+```
+
+Per gli input audio, puoi creare un [`Wav2Vec2FeatureExtractor`] e personalizzare i parametri in modo simile:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> w2v2_extractor = Wav2Vec2FeatureExtractor()
+>>> print(w2v2_extractor)
+Wav2Vec2FeatureExtractor {
+ "do_normalize": true,
+ "feature_extractor_type": "Wav2Vec2FeatureExtractor",
+ "feature_size": 1,
+ "padding_side": "right",
+ "padding_value": 0.0,
+ "return_attention_mask": false,
+ "sampling_rate": 16000
+}
+```
+
+## Processore
+
+Per modelli che supportano attività multimodali, 🤗 Transformers offre una classe di processore che racchiude comodamente un estrattore di caratteristiche e un tokenizer in un unico oggetto. Ad esempio, utilizziamo [`Wav2Vec2Processor`] per un'attività di riconoscimento vocale automatico (ASR). ASR trascrive l'audio in testo, quindi avrai bisogno di un estrattore di caratteristiche e di un tokenizer.
+
+Crea un estrattore di feature per gestire gli input audio:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> feature_extractor = Wav2Vec2FeatureExtractor(padding_value=1.0, do_normalize=True)
+```
+
+Crea un tokenizer per gestire gli input di testo:
+
+```py
+>>> from transformers import Wav2Vec2CTCTokenizer
+
+>>> tokenizer = Wav2Vec2CTCTokenizer(vocab_file="my_vocab_file.txt")
+```
+
+Combinare l'estrattore di caratteristiche e il tokenizer in [`Wav2Vec2Processor`]:
+
+```py
+>>> from transformers import Wav2Vec2Processor
+
+>>> processor = Wav2Vec2Processor(feature_extractor=feature_extractor, tokenizer=tokenizer)
+```
+
+Con due classi di base - configurazione e modello - e una classe di preelaborazione aggiuntiva (tokenizer, estrattore di caratteristiche o processore), puoi creare qualsiasi modello supportato da 🤗 Transformers. Ognuna di queste classi base è configurabile, consentendoti di utilizzare gli attributi specifici che desideri. È possibile impostare facilmente un modello per l'addestramento o modificare un modello preallenato esistente per la messa a punto.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/custom_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/custom_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..94626937eb81be5a8d33b38dfbc51385be4ca46f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/custom_models.md
@@ -0,0 +1,359 @@
+
+
+# Condividere modelli personalizzati
+La libreria 🤗 Transformers è studiata per essere facilmente estendibile. Il codice di ogni modello è interamente
+situato in una sottocartella del repository senza alcuna astrazione, perciò puoi facilmente copiare il file di un
+modello e modificarlo in base ai tuoi bisogni.
+
+Se stai scrivendo un nuovo modello, potrebbe essere più semplice iniziare da zero. In questo tutorial, ti mostreremo
+come scrivere un modello personalizzato e la sua configurazione in modo che possa essere utilizzato all’interno di
+Transformers, e come condividerlo con la community (assieme al relativo codice) così che tutte le persone possano usarlo, anche
+se non presente nella libreria 🤗 Transformers.
+
+Illustriamo tutto questo su un modello ResNet, avvolgendo la classe ResNet della
+[libreria timm](https://github.com/rwightman/pytorch-image-models) in un [`PreTrainedModel`].
+
+## Scrivere una configurazione personalizzata
+Prima di iniziare a lavorare al modello, scriviamone la configurazione. La configurazione di un modello è un oggetto
+che contiene tutte le informazioni necessarie per la build del modello. Come vedremo nella prossima sezione, il
+modello può soltanto essere inizializzato tramite `config`, per cui dovremo rendere tale oggetto più completo possibile.
+
+Nel nostro esempio, prenderemo un paio di argomenti della classe ResNet che potremmo voler modificare.
+Configurazioni differenti ci daranno quindi i differenti possibili tipi di ResNet. Salveremo poi questi argomenti,
+dopo averne controllato la validità.
+
+```python
+from transformers import PretrainedConfig
+from typing import List
+
+
+class ResnetConfig(PretrainedConfig):
+ model_type = "resnet"
+
+ def __init__(
+ self,
+ block_type="bottleneck",
+ layers: List[int] = [3, 4, 6, 3],
+ num_classes: int = 1000,
+ input_channels: int = 3,
+ cardinality: int = 1,
+ base_width: int = 64,
+ stem_width: int = 64,
+ stem_type: str = "",
+ avg_down: bool = False,
+ **kwargs,
+ ):
+ if block_type not in ["basic", "bottleneck"]:
+ raise ValueError(f"`block_type` must be 'basic' or bottleneck', got {block_type}.")
+ if stem_type not in ["", "deep", "deep-tiered"]:
+ raise ValueError(f"`stem_type` must be '', 'deep' or 'deep-tiered', got {stem_type}.")
+
+ self.block_type = block_type
+ self.layers = layers
+ self.num_classes = num_classes
+ self.input_channels = input_channels
+ self.cardinality = cardinality
+ self.base_width = base_width
+ self.stem_width = stem_width
+ self.stem_type = stem_type
+ self.avg_down = avg_down
+ super().__init__(**kwargs)
+```
+
+Le tre cose più importanti da ricordare quando scrivi le tue configurazioni sono le seguenti:
+- Devi ereditare da `Pretrainedconfig`,
+- Il metodo `__init__` del tuo `Pretrainedconfig` deve accettare i kwargs,
+- I `kwargs` devono essere passati alla superclass `__init__`
+
+L’eredità è importante per assicurarsi di ottenere tutte le funzionalità della libreria 🤗 transformers,
+mentre gli altri due vincoli derivano dal fatto che un `Pretrainedconfig` ha più campi di quelli che stai settando.
+Quando ricarichi una config da un metodo `from_pretrained`, questi campi devono essere accettati dalla tua config e
+poi inviati alla superclasse.
+
+Definire un `model_type` per la tua configurazione (qua `model_type = “resnet”`) non è obbligatorio, a meno che tu
+non voglia registrare il modello con le classi Auto (vedi l'ultima sezione).
+
+Una volta completato, puoi facilmente creare e salvare la tua configurazione come faresti con ogni altra configurazione
+di modelli della libreria. Ecco come possiamo creare la config di un resnet50d e salvarlo:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d_config.save_pretrained("custom-resnet")
+```
+
+Questo salverà un file chiamato `config.json` all'interno della cartella `custom-resnet`. Potrai poi ricaricare la tua
+config con il metodo `from_pretrained`.
+
+```py
+resnet50d_config = ResnetConfig.from_pretrained("custom-resnet")
+```
+
+Puoi anche usare qualunque altro metodo della classe [`PretrainedConfig`], come [`~PretrainedConfig.push_to_hub`]
+per caricare direttamente la tua configurazione nell'hub.
+
+## Scrivere un modello personalizzato
+
+Ora che abbiamo la nostra configurazione ResNet, possiamo continuare a scrivere il modello. In realtà, ne scriveremo
+due: uno che estrae le features nascoste da una batch di immagini (come [`BertModel`]) e uno che è utilizzabile per
+la classificazione di immagini (come [`BertModelForSequenceClassification`]).
+
+Come abbiamo menzionato in precedenza, scriveremo soltanto un wrapper del modello, per mantenerlo semplice ai fini di
+questo esempio. L'unica cosa che dobbiamo fare prima di scrivere questa classe è una mappatura fra i tipi di blocco e
+le vere classi dei blocchi. Successivamente il modello è definito tramite la configurazione, passando tutto quanto alla
+classe `ResNet`.
+
+```py
+from transformers import PreTrainedModel
+from timm.models.resnet import BasicBlock, Bottleneck, ResNet
+from .configuration_resnet import ResnetConfig
+
+
+BLOCK_MAPPING = {"basic": BasicBlock, "bottleneck": Bottleneck}
+
+
+class ResnetModel(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor):
+ return self.model.forward_features(tensor)
+```
+
+Per il modello che classificherà le immagini, cambiamo soltanto il metodo forward:
+
+```py
+import torch
+
+
+class ResnetModelForImageClassification(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor, labels=None):
+ logits = self.model(tensor)
+ if labels is not None:
+ loss = torch.nn.functional.cross_entropy(logits, labels)
+ return {"loss": loss, "logits": logits}
+ return {"logits": logits}
+```
+
+Nota come, in entrambi i casi, ereditiamo da `PreTrainedModel` e chiamiamo l'inizializzazione della superclasse
+con il metodo `config` (un po' come quando scrivi un normale `torch.nn.Module`). La riga che imposta la `config_class`
+non è obbligatoria, a meno che tu non voglia registrare il modello con le classi Auto (vedi l'ultima sezione).
+
+
+
+Se il tuo modello è molto simile a un modello all'interno della libreria, puoi ri-usare la stessa configurazione di quel modello.
+
+
+
+Puoi fare in modo che il tuo modello restituisca in output qualunque cosa tu voglia, ma far restituire un dizionario
+come abbiamo fatto per `ResnetModelForImageClassification`, con la funzione di perdita inclusa quando vengono passate le labels,
+renderà il tuo modello direttamente utilizzabile all'interno della classe [`Trainer`]. Utilizzare altri formati di output va bene
+se hai in progetto di utilizzare un tuo loop di allenamento, o se utilizzerai un'altra libreria per l'addestramento.
+
+Ora che abbiamo la classe del nostro modello, creiamone uno:
+
+```py
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+```
+
+Ribadiamo, puoi usare qualunque metodo dei [`PreTrainedModel`], come [`~PreTrainedModel.save_pretrained`] o
+[`~PreTrainedModel.push_to_hub`]. Utilizzeremo quest'ultimo nella prossima sezione, e vedremo come caricare i pesi del
+modello assieme al codice del modello stesso. Ma prima, carichiamo alcuni pesi pre-allenati all'interno del nostro modello.
+
+Nel tuo caso specifico, probabilmente allenerai il tuo modello sui tuoi dati. Per velocizzare in questo tutorial,
+utilizzeremo la versione pre-allenata del resnet50d. Dato che il nostro modello è soltanto un wrapper attorno a quel modello,
+sarà facile trasferirne i pesi:
+
+```py
+import timm
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+Vediamo adesso come assicurarci che quando facciamo [`~PreTrainedModel.save_pretrained`] o [`~PreTrainedModel.push_to_hub`],
+il codice del modello venga salvato.
+
+## Inviare il codice all'Hub
+
+
+
+Questa API è sperimentale e potrebbe avere alcuni cambiamenti nei prossimi rilasci.
+
+
+
+Innanzitutto, assicurati che il tuo modello sia completamente definito in un file `.py`. Può sfruttare import relativi
+ad altri file, purchè questi siano nella stessa directory (non supportiamo ancora sotto-moduli per questa funzionalità).
+Per questo esempio, definiremo un file `modeling_resnet.py` e un file `configuration_resnet.py` in una cartella dell'attuale
+working directory chiamata `resnet_model`. Il file configuration contiene il codice per `ResnetConfig` e il file modeling
+contiene il codice di `ResnetModel` e `ResnetModelForImageClassification`.
+
+```
+.
+└── resnet_model
+ ├── __init__.py
+ ├── configuration_resnet.py
+ └── modeling_resnet.py
+```
+
+Il file `__init__.py` può essere vuoto, serve solo perchè Python capisca che `resnet_model` può essere utilizzato come un modulo.
+
+
+
+Se stai copiando i file relativi alla modellazione della libreria, dovrai sostituire tutti gli import relativi in cima al file con import del
+ pacchetto `transformers`.
+
+
+
+Nota che puoi ri-utilizzare (o usare come sottoclassi) un modello/configurazione esistente.
+
+Per condividere il tuo modello con la community, segui questi passi: prima importa il modello ResNet e la sua configurazione
+dai nuovi file creati:
+
+```py
+from resnet_model.configuration_resnet import ResnetConfig
+from resnet_model.modeling_resnet import ResnetModel, ResnetModelForImageClassification
+```
+
+Dopodichè dovrai dire alla libreria che vuoi copiare i file con il codice di quegli oggetti quando utilizzi il metodo
+`save_pretrained` e registrarli in modo corretto con una Auto classe (specialmente per i modelli). Utilizza semplicemente:
+
+```py
+ResnetConfig.register_for_auto_class()
+ResnetModel.register_for_auto_class("AutoModel")
+ResnetModelForImageClassification.register_for_auto_class("AutoModelForImageClassification")
+```
+
+Nota che non c'è bisogno di specificare una Auto classe per la configurazione (c'è solo una Auto classe per le configurazioni,
+[`AutoConfig`], ma è diversa per i modelli). Il tuo modello personalizato potrebbe essere utilizzato per diverse tasks,
+per cui devi specificare quale delle classi Auto è quella corretta per il tuo modello.
+
+Successivamente, creiamo i modelli e la config come abbiamo fatto in precedenza:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+Adesso, per inviare il modello all'Hub, assicurati di aver effettuato l'accesso. Lancia dal tuo terminale:
+
+```bash
+huggingface-cli login
+```
+
+O da un notebook:
+
+```py
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+Potrai poi inviare il tutto sul tuo profilo (o di un'organizzazione di cui fai parte) in questo modo:
+
+```py
+resnet50d.push_to_hub("custom-resnet50d")
+```
+
+Oltre ai pesi del modello e alla configurazione in formato json, questo ha anche copiato i file `.py` modeling e
+configuration all'interno della cartella `custom-resnet50d` e ha caricato i risultati sull'Hub. Puoi controllare
+i risultati in questa [model repo](https://huggingface.co/sgugger/custom-resnet50d).
+
+Puoi controllare il tutorial di condivisione [tutorial di condivisione](model_sharing) per più informazioni sul
+metodo con cui inviare all'Hub.
+
+## Usare un modello con codice personalizzato
+
+Puoi usare ogni configurazione, modello o tokenizer con file di codice personalizzati nella sua repository
+con le classi Auto e il metodo `from_pretrained`. Tutti i files e il codice caricati sull'Hub sono scansionati da malware
+(fai riferimento alla documentazione [Hub security](https://huggingface.co/docs/hub/security#malware-scanning) per più informazioni),
+ma dovresti comunque assicurarti dell'affidabilità del codice e dell'autore per evitare di eseguire codice dannoso sulla tua macchina.
+Imposta `trust_remote_code=True` per usare un modello con codice personalizzato:
+
+```py
+from transformers import AutoModelForImageClassification
+
+model = AutoModelForImageClassification.from_pretrained("sgugger/custom-resnet50d", trust_remote_code=True)
+```
+
+Inoltre, raccomandiamo fortemente di passare un hash del commit come `revision` per assicurarti che le autrici o gli autori del modello
+non abbiano modificato il codice con alcune nuove righe dannose (a meno che non ti fidi completamente della fonte):
+
+```py
+commit_hash = "ed94a7c6247d8aedce4647f00f20de6875b5b292"
+model = AutoModelForImageClassification.from_pretrained(
+ "sgugger/custom-resnet50d", trust_remote_code=True, revision=commit_hash
+)
+```
+
+Nota che quando cerchi la storia dei commit della repo del modello sull'Hub, c'è un bottone con cui facilmente copiare il
+commit hash di ciascun commit.
+
+## Registrare un modello con codice personalizzato nelle classi Auto
+
+Se stai scrivendo una libreria che estende 🤗 Transformers, potresti voler estendere le classi Auto per includere il tuo modello.
+Questo è diverso dall'inviare codice nell'Hub: gli utenti dovranno importare la tua libreria per ottenere il modello personalizzato
+(anzichè scaricare automaticamente il modello dall'Hub).
+
+Finchè il tuo file di configurazione ha un attributo `model_type` diverso dai model types esistenti, e finchè le tue
+classi modello hanno i corretti attributi `config_class`, potrai semplicemente aggiungerli alle classi Auto come segue:
+
+```py
+from transformers import AutoConfig, AutoModel, AutoModelForImageClassification
+
+AutoConfig.register("resnet", ResnetConfig)
+AutoModel.register(ResnetConfig, ResnetModel)
+AutoModelForImageClassification.register(ResnetConfig, ResnetModelForImageClassification)
+```
+
+Nota che il primo argomento utilizzato quando registri la configurazione di un modello personalizzato con [`AutoConfig`]
+deve corrispondere al `model_type` della tua configurazione personalizzata, ed il primo argomento utilizzato quando
+registri i tuoi modelli personalizzati in una qualunque classe Auto del modello deve corrispondere alla `config_class`
+di quei modelli.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/debugging.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/debugging.md
new file mode 100644
index 0000000000000000000000000000000000000000..5c1dab51bd11793a62eabc916c7bbf7e95209934
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/debugging.md
@@ -0,0 +1,318 @@
+
+
+# Debugging
+
+## Debug dei problemi di rete multi-GPU
+
+Quando addestri o fai inferenza con `DistributedDataParallel` e GPU multiple, se si verificano problemi di intercomunicazione tra processi e/o nodi, puoi utilizzare il seguente script per diagnosticare i problemi della rete.
+
+```bash
+wget https://raw.githubusercontent.com/huggingface/transformers/main/scripts/distributed/torch-distributed-gpu-test.py
+```
+
+Per esempio per testare come 2 GPU interagiscono fai:
+
+```bash
+python -m torch.distributed.run --nproc_per_node 2 --nnodes 1 torch-distributed-gpu-test.py
+```
+
+Se entrambi i processi sono in grado di comunicare tra loro e di allocare la memoria della GPU, ciascuno di essi stamperà lo stato OK.
+
+Per più GPU o nodi adatta gli argumenti nello script.
+
+All'interno dello script di diagnostica troverai molti altri dettagli e anche una guida per eseguirlo in ambiente SLURM.
+
+Un livello di debug superiore è aggiungere la variabile d'ambiente `NCCL_DEBUG=INFO` come di seguito:
+
+```bash
+NCCL_DEBUG=INFO python -m torch.distributed.run --nproc_per_node 2 --nnodes 1 torch-distributed-gpu-test.py
+```
+
+In questo modo si scaricano molte informazioni di debug relative a NCCL, che puoi cercare online in caso di problemi. Oppure, se non hai la sicurezza di come interpretare l'output, puoi condividere il file di log in una Issue.
+
+## Rilevamento di Underflow e Overflow
+
+
+
+Questa funzionalità al momento è disponibile solo per PyTorch.
+
+
+
+
+
+Per addestramento multi-GPU richiede DDP (`torch.distributed.launch`).
+
+
+
+
+
+Questa funzionalità può essere usata con modelli basati su `nn.Module`.
+
+
+
+Se inizi a ottenere `loss=NaN` o il modello presenta qualche altro comportamento anomalo a causa di valori `inf` o `nan` in
+attivazioni o nei pesi, è necessario scoprire dove si verifica il primo underflow o overflow e cosa lo ha determinato. Fortunatamente
+è possibile farlo facilmente attivando un modulo speciale che effettuerà il rilevamento automaticamente.
+
+Se stai usando [`Trainer`], hai bisogno di aggiungere solo:
+
+```bash
+--debug underflow_overflow
+```
+
+ai normali argomenti della riga di comando, o passa `debug="underflow_overflow"` quando viene creato l'oggetto
+[`TrainingArguments`].
+
+Se stai usando il tuo ciclo di allenamento o un altro trainer, puoi ottenere lo stesso risultato con:
+
+```python
+from .debug_utils import DebugUnderflowOverflow
+
+debug_overflow = DebugUnderflowOverflow(model)
+```
+
+[`~debug_utils.DebugUnderflowOverflow`] inserisce dei ganci nel modello che dopo ogni chiamata
+testeranno le variabili di ingresso e di uscita e anche i pesi del modulo corrispondente. Non appena viene rilevato `inf` o
+o `nan` in almeno un elemento delle attivazioni o dei pesi, il programma lo notifica e stampa un rapporto come il seguente (questo è stato rilevato con `google/mt5-small` sotto fp16 mixed precision):
+
+```
+Detected inf/nan during batch_number=0
+Last 21 forward frames:
+abs min abs max metadata
+ encoder.block.1.layer.1.DenseReluDense.dropout Dropout
+0.00e+00 2.57e+02 input[0]
+0.00e+00 2.85e+02 output
+[...]
+ encoder.block.2.layer.0 T5LayerSelfAttention
+6.78e-04 3.15e+03 input[0]
+2.65e-04 3.42e+03 output[0]
+ None output[1]
+2.25e-01 1.00e+04 output[2]
+ encoder.block.2.layer.1.layer_norm T5LayerNorm
+8.69e-02 4.18e-01 weight
+2.65e-04 3.42e+03 input[0]
+1.79e-06 4.65e+00 output
+ encoder.block.2.layer.1.DenseReluDense.wi_0 Linear
+2.17e-07 4.50e+00 weight
+1.79e-06 4.65e+00 input[0]
+2.68e-06 3.70e+01 output
+ encoder.block.2.layer.1.DenseReluDense.wi_1 Linear
+8.08e-07 2.66e+01 weight
+1.79e-06 4.65e+00 input[0]
+1.27e-04 2.37e+02 output
+ encoder.block.2.layer.1.DenseReluDense.dropout Dropout
+0.00e+00 8.76e+03 input[0]
+0.00e+00 9.74e+03 output
+ encoder.block.2.layer.1.DenseReluDense.wo Linear
+1.01e-06 6.44e+00 weight
+0.00e+00 9.74e+03 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.DenseReluDense T5DenseGatedGeluDense
+1.79e-06 4.65e+00 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.dropout Dropout
+3.18e-04 6.27e+04 input[0]
+0.00e+00 inf output
+```
+
+L'output di esempio è stato tagliato al centro per brevità.
+
+La seconda colonna mostra il valore dell'elemento più grande in assoluto,così se osserviamo da vicino gli ultimi istanti,
+input e output sono nel range di `1e4`. Questo addestramento è stato eseguito con una mixed precision fp16 e l'ultimo passo usciva fuori (sotto `fp16` il valore più grande prima di `inf` è `64e3`). Per evitare overflows sotto `fp16` le attivazionioni devono rimanere molto al di sotto di `1e4`, perché `1e4 * 1e4 = 1e8` quindi qualsiasi moltiplicazione di matrice con grandi attivazioni porterà a una condizione di overflow numerico.
+
+All'inizio della traccia è possibile scoprire a quale lotto si è verificato il problema (questo `Detected inf/nan during batch_number=0` significa che il problema si è verificato nel primo lotto).
+
+Ogni frame segnalato inizia dichiarando la voce completamente qualificata per il modulo corrispondente per il quale il frame è stato segnalato.
+Se osserviamo il seguente frame:
+
+```
+ encoder.block.2.layer.1.layer_norm T5LayerNorm
+8.69e-02 4.18e-01 weight
+2.65e-04 3.42e+03 input[0]
+1.79e-06 4.65e+00 output
+```
+
+Questo, `encoder.block.2.layer.1.layer_norm` indica che si tratta di un layer norm nel primo layer, del secondo blocco dell'encoder. E le chiamata specifica di `forward` è `T5LayerNorm`.
+
+Osserviamo gli ultimi frame del report:
+
+```
+Detected inf/nan during batch_number=0
+Last 21 forward frames:
+abs min abs max metadata
+[...]
+ encoder.block.2.layer.1.DenseReluDense.wi_0 Linear
+2.17e-07 4.50e+00 weight
+1.79e-06 4.65e+00 input[0]
+2.68e-06 3.70e+01 output
+ encoder.block.2.layer.1.DenseReluDense.wi_1 Linear
+8.08e-07 2.66e+01 weight
+1.79e-06 4.65e+00 input[0]
+1.27e-04 2.37e+02 output
+ encoder.block.2.layer.1.DenseReluDense.wo Linear
+1.01e-06 6.44e+00 weight
+0.00e+00 9.74e+03 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.DenseReluDense T5DenseGatedGeluDense
+1.79e-06 4.65e+00 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.dropout Dropout
+3.18e-04 6.27e+04 input[0]
+0.00e+00 inf output
+```
+
+L'ultimo frame report per la funzione `Dropout.forward` con la prima voce per l'unico input e la seconda per l'unico output. Si può notare che è stato richiamato da un attibuto `dropout` dentro la classe `DenseReluDense`. Si può notare che ciò è avvenuto durante il primo strato, del 2° blocco, durante il primissimo lotto. Infine, gli elementi di input più grandi in assoluto sono stati `6.27e+04` e l'equivalente per l'output era `inf`.
+
+Puoi vedere qui, che `T5DenseGatedGeluDense.forward` risulta in output activations, il cui valore massimo assoluto era circa 62,7K, che è molto vicino al limite massimo di 64K di fp16. Nel prossimo frame abbiamo `Dropout` che rinormalizza i pesi, dopo aver azzerato alcuni elementi, il che spinge il valore massimo assoluto a più di 64K e si verifica un overflow.(`inf`).
+
+Come puoi notare, è nei frames precedenti che occorre esaminare quando i numeri iniziano a diventare molto grandi per i valori fp16.
+
+Confrontiamo il report al codice `models/t5/modeling_t5.py`:
+
+```python
+class T5DenseGatedGeluDense(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.wi_0 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wi_1 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wo = nn.Linear(config.d_ff, config.d_model, bias=False)
+ self.dropout = nn.Dropout(config.dropout_rate)
+ self.gelu_act = ACT2FN["gelu_new"]
+
+ def forward(self, hidden_states):
+ hidden_gelu = self.gelu_act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+```
+
+Ora è facile vedere la chiamata `dropout`, e tutte le chiamate precedenti.
+
+Poiché il rilevamento avviene in un avanzamento (forward hook in eng.), i rapporti vengono creati immeditamente dopo ogni rientro da `forward` (forward returns in eng.).
+
+Tornando al rapporto completo, per agire e risolvere il problema, dobbiamo andare qualche frame più in alto, dove i numeri hanno iniziato a salire, e probabilmente passare alla modalità `fp32`, in modo che i numeri non trabocchino quando vengono moltiplicati o sommati. Naturalmente, potrebbero esserci altre soluzioni. Per esempio, potremmo spegnere temporanemante `amp` se è abilitato, successivamente spostare `forward` in un helper wrapper, come:
+
+```python
+def _forward(self, hidden_states):
+ hidden_gelu = self.gelu_act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+import torch
+
+
+def forward(self, hidden_states):
+ if torch.is_autocast_enabled():
+ with torch.cuda.amp.autocast(enabled=False):
+ return self._forward(hidden_states)
+ else:
+ return self._forward(hidden_states)
+```
+
+Poiché il rilevatore automatico riporta solo gli ingressi e le uscite di fotogrammi completi, una volta che si sa dove cercare, si può
+analizzare anche le fasi intermedie di una specifica funzione `forward`. In alcuni casi puoi usare la funzione di supporto `detect_overflow` per indirizzare il rilevatore dove preferisci, ad esempio:
+
+```python
+from debug_utils import detect_overflow
+
+
+class T5LayerFF(nn.Module):
+ [...]
+
+ def forward(self, hidden_states):
+ forwarded_states = self.layer_norm(hidden_states)
+ detect_overflow(forwarded_states, "after layer_norm")
+ forwarded_states = self.DenseReluDense(forwarded_states)
+ detect_overflow(forwarded_states, "after DenseReluDense")
+ return hidden_states + self.dropout(forwarded_states)
+```
+
+Si può vedere che abbiamo aggiunto 2 di questi e ora teniamo traccia se `inf` o `nan` per `forwarded_states` è stato rilevato
+da qualche parte.
+
+In realtà, il rilevatore li riporta già, perché ciascuna delle chiamate nell'esempio precedente è un `nn.Module`, ma
+diciamo che se avessimo dei calcoli diretti locali, questo è il modo in cui lo faremmo.
+
+Inoltre, se si istanzia il debugger nel proprio codice, è possibile modificare il numero di fotogrammi stampati rispetto a
+predefinito, ad esempio.:
+
+```python
+from .debug_utils import DebugUnderflowOverflow
+
+debug_overflow = DebugUnderflowOverflow(model, max_frames_to_save=100)
+```
+
+### Tracciamento della mistura assoluta del lotto specifico e del valore massimo
+
+La stessa classe di debug può essere utilizzata per il tracciamento per-batch con la funzione di rilevamento di underflow/overflow disattivata.
+
+Supponiamo di voler osservare i valori minimi e massimi assoluti per tutti gli ingredienti di ogni chiamata `forward` di un dato lotto.
+lotto, e che lo si voglia fare solo per i lotti 1 e 3. Si istanzia questa classe come:
+
+```python
+debug_overflow = DebugUnderflowOverflow(model, trace_batch_nums=[1, 3])
+```
+
+Ora i batch completi 1 e 3 saranno tracciati utilizzando lo stesso formato del rilevatore di underflow/overflow.
+
+I batches sono 0-indexed.
+
+Questo è utile se si sa che il programma inizia a comportarsi male dopo un certo numero di batch, in modo da poter avanzare velocemente fino a quell'area.
+direttamente a quell'area. Ecco un esempio di output troncato per questa configurazione:
+
+```
+ *** Starting batch number=1 ***
+abs min abs max metadata
+ shared Embedding
+1.01e-06 7.92e+02 weight
+0.00e+00 2.47e+04 input[0]
+5.36e-05 7.92e+02 output
+[...]
+ decoder.dropout Dropout
+1.60e-07 2.27e+01 input[0]
+0.00e+00 2.52e+01 output
+ decoder T5Stack
+ not a tensor output
+ lm_head Linear
+1.01e-06 7.92e+02 weight
+0.00e+00 1.11e+00 input[0]
+6.06e-02 8.39e+01 output
+ T5ForConditionalGeneration
+ not a tensor output
+
+ *** Starting batch number=3 ***
+abs min abs max metadata
+ shared Embedding
+1.01e-06 7.92e+02 weight
+0.00e+00 2.78e+04 input[0]
+5.36e-05 7.92e+02 output
+[...]
+```
+
+Qui verrà scaricato un numero enorme di fotogrammi, tanti quanti sono le chiamate in avanti nel modello, quindi può essere o non essere quello che volete, ma a volte può essere più utile usarlo di un classico debugger. Per esempio, se il problema inizia a verificarsi a partire dal lotto numero 150. Quindi è possibile scaricare le tracce dei lotti 149 e 150 e confrontare i punti in cui i numeri hanno iniziato a divergere.
+
+È inoltre possibile specificare il numero di batch dopo il quale interrompere l'addestramento, con:
+
+```python
+debug_overflow = DebugUnderflowOverflow(model, trace_batch_nums=[1, 3], abort_after_batch_num=3)
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/index.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/index.md
new file mode 100644
index 0000000000000000000000000000000000000000..76cdc0ad246104f15a291413e7f03b9b662ead5f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/index.md
@@ -0,0 +1,300 @@
+
+
+# 🤗 Transformers
+
+Machine Learning allo stato dell'arte per PyTorch, TensorFlow e JAX.
+
+🤗 Transformers fornisce delle API per scaricare in modo semplice e allenare modelli pre-allenati allo stato dell'arte. L'utilizzo di modelli pre-allenati può ridurre i tuoi costi computazionali, l'impatto ambientale, e farti risparmiare il tempo che utilizzeresti per allenare un modello da zero. I modelli possono essere utilizzati in diverse modalità come ad esempio:
+
+* 📝 Testo: classificazione del testo, estrazione delle informazioni, rispondere a domande, riassumere, traduzione e generazione del testo in più di 100 lingue.
+* 🖼️ Immagini: classificazione di immagini, rilevazione di oggetti e segmentazione.
+* 🗣️ Audio: riconoscimento vocale e classificazione dell'audio.
+* 🐙 Multimodale: rispondere a domande inerenti dati tabulari, riconoscimento ottico dei caratteri, estrazione di informazioni a partire da documenti scannerizzati, classificazione di video e risposta visuale a domande.
+
+La nostra libreria supporta un'integrazione perfetta tra tre delle librerie per il deep learning più popolari: [PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/) e [JAX](https://jax.readthedocs.io/en/latest/). Allena il tuo modello in tre righe di codice in un framework, e caricalo per l'inferenza in un altro.
+
+Ogni architettura di 🤗 Transformers è definita in un modulo Python indipendente così da poter essere personalizzata in modo semplice per la ricerca e gli esperimenti.
+
+## Se stai cercando supporto personalizzato dal team di Hugging Face
+
+
+
+
+## Contenuti
+
+La documentazione è organizzata in cinque parti:
+
+- **INIZIARE** contiene un tour rapido e le istruzioni di installazione per cominciare ad utilizzare 🤗 Transformers.
+- **TUTORIALS** è un buon posto da cui iniziare se per te la nostra libreria è nuova. Questa sezione ti aiuterà ad acquisire le competenze basilari di cui hai bisogno per iniziare ad utilizzare 🤗 Transformers.
+- **GUIDE PRATICHE** ti mostrerà come raggiungere obiettivi specifici come fare fine-tuning di un modello pre-allenato per la modellizzazione del linguaggio o come creare una testa per un modello personalizzato.
+- **GUIDE CONCETTUALI** fornisce discussioni e spiegazioni dei concetti sottostanti alle idee dietro ai modelli, compiti, e la filosofia di progettazione di 🤗 Transformers.
+- **API** descrive ogni classe e funzione, raggruppate in:
+ - **CLASSI PRINCIPALI** per le classi principali che espongono le API importanti della libreria.
+ - **MODELLI** per le classi e le funzioni relative ad ogni modello implementato all'interno della libreria.
+ - **HELPERS INTERNI** per le classi e le funzioni che utilizziamo internamente.
+
+La libreria attualmente contiene implementazioni in JAX, PyTorch e TensorFlow, pesi di modelli pre-allenati, script di utilizzo e strumenti di conversione per i seguenti modelli.
+
+### Modelli supportati
+
+
+
+1. **[ALBERT](model_doc/albert)** (da Google Research e l'Istituto Tecnologico di Chicago) rilasciato con il paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942), da Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
+1. **[ALIGN](model_doc/align)** (from Google Research) rilasciato con il paper [Scaling Up Visual and Vision-Language Representation Learning With Noisy Text Supervision](https://arxiv.org/abs/2102.05918) da Chao Jia, Yinfei Yang, Ye Xia, Yi-Ting Chen, Zarana Parekh, Hieu Pham, Quoc V. Le, Yunhsuan Sung, Zhen Li, Tom Duerig.
+1. **[BART](model_doc/bart)** (da Facebook) rilasciato con il paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461) da Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov e Luke Zettlemoyer.
+1. **[BARThez](model_doc/barthez)** (da politecnico di École) rilasciato con il paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321) da Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
+1. **[BARTpho](model_doc/bartpho)** (da VinAI Research) rilasciato con il paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701) da Nguyen Luong Tran, Duong Minh Le e Dat Quoc Nguyen.
+1. **[BEiT](model_doc/beit)** (da Microsoft) rilasciato con il paper [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) da Hangbo Bao, Li Dong, Furu Wei.
+1. **[BERT](model_doc/bert)** (da Google) rilasciato con il paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) da Jacob Devlin, Ming-Wei Chang, Kenton Lee e Kristina Toutanova.
+1. **[BERTweet](model_doc/bertweet)** (da VinAI Research) rilasciato con il paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) da Dat Quoc Nguyen, Thanh Vu e Anh Tuan Nguyen.
+1. **[BERT For Sequence Generation](model_doc/bert-generation)** (da Google) rilasciato con il paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) da Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[BigBird-RoBERTa](model_doc/big_bird)** (da Google Research) rilasciato con il paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) da Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (v Google Research) rilasciato con il paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) da Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[Blenderbot](model_doc/blenderbot)** (da Facebook) rilasciato con il paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) da Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BlenderbotSmall](model_doc/blenderbot-small)** (da Facebook) rilasciato con il paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) da Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BORT](model_doc/bort)** (da Alexa) rilasciato con il paper [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499) da Adrian de Wynter e Daniel J. Perry.
+1. **[ByT5](model_doc/byt5)** (da Google Research) rilasciato con il paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) da Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
+1. **[CamemBERT](model_doc/camembert)** (da Inria/Facebook/Sorbonne) rilasciato con il paper [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) da Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah e Benoît Sagot.
+1. **[CANINE](model_doc/canine)** (da Google Research) rilasciato con il paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874) da Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
+1. **[ConvNeXT](model_doc/convnext)** (da Facebook AI) rilasciato con il paper [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) da Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+1. **[ConvNeXTV2](model_doc/convnextv2)** (da Facebook AI) rilasciato con il paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) da Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CLIP](model_doc/clip)** (da OpenAI) rilasciato con il paper [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) da Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
+1. **[ConvBERT](model_doc/convbert)** (da YituTech) rilasciato con il paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) da Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
+1. **[CPM](model_doc/cpm)** (dalla Università di Tsinghua) rilasciato con il paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413) da Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+1. **[CTRL](model_doc/ctrl)** (da Salesforce) rilasciato con il paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) da Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong e Richard Socher.
+1. **[CvT](model_doc/cvt)** (da Microsoft) rilasciato con il paper [CvT: Introducing Convolutions to Vision Transformers](https://arxiv.org/abs/2103.15808) da Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang.
+1. **[Data2Vec](model_doc/data2vec)** (da Facebook) rilasciato con il paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555) da Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
+1. **[DeBERTa](model_doc/deberta)** (da Microsoft) rilasciato con il paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) da Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[DeBERTa-v2](model_doc/deberta-v2)** (da Microsoft) rilasciato con il paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) da Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[Decision Transformer](model_doc/decision_transformer)** (da Berkeley/Facebook/Google) rilasciato con il paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) da Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+1. **[DiT](model_doc/dit)** (da Microsoft Research) rilasciato con il paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378) da Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
+1. **[DeiT](model_doc/deit)** (da Facebook) rilasciato con il paper [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877) da Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
+1. **[DETR](model_doc/detr)** (da Facebook) rilasciato con il paper [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872) da Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
+1. **[DialoGPT](model_doc/dialogpt)** (da Microsoft Research) rilasciato con il paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536) da Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
+1. **[DistilBERT](model_doc/distilbert)** (da HuggingFace), rilasciato assieme al paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108) da Victor Sanh, Lysandre Debut e Thomas Wolf. La stessa tecnica è stata applicata per comprimere GPT2 in [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), RoBERTa in [DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), Multilingual BERT in [DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) and a German version of DistilBERT.
+1. **[DPR](model_doc/dpr)** (da Facebook) rilasciato con il paper [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906) da Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, e Wen-tau Yih.
+1. **[DPT](master/model_doc/dpt)** (da Intel Labs) rilasciato con il paper [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413) da René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+1. **[EfficientNet](model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://arxiv.org/abs/1905.11946) by Mingxing Tan and Quoc V. Le.
+1. **[EncoderDecoder](model_doc/encoder-decoder)** (da Google Research) rilasciato con il paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) da Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[ELECTRA](model_doc/electra)** (da Google Research/Stanford University) rilasciato con il paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555) da Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
+1. **[FlauBERT](model_doc/flaubert)** (da CNRS) rilasciato con il paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) da Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
+1. **[FLAVA](model_doc/flava)** (da Facebook AI) rilasciato con il paper [FLAVA: A Foundational Language And Vision Alignment Model](https://arxiv.org/abs/2112.04482) da Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, e Douwe Kiela.
+1. **[FNet](model_doc/fnet)** (da Google Research) rilasciato con il paper [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) da James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
+1. **[Funnel Transformer](model_doc/funnel)** (da CMU/Google Brain) rilasciato con il paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236) da Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
+1. **[GLPN](model_doc/glpn)** (da KAIST) rilasciato con il paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) da Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+1. **[GPT](model_doc/openai-gpt)** (da OpenAI) rilasciato con il paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) da Alec Radford, Karthik Narasimhan, Tim Salimans e Ilya Sutskever.
+1. **[GPT-2](model_doc/gpt2)** (da OpenAI) rilasciato con il paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) da Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei e Ilya Sutskever.
+1. **[GPT-J](model_doc/gptj)** (da EleutherAI) rilasciato nel repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) da Ben Wang e Aran Komatsuzaki.
+1. **[GPT Neo](model_doc/gpt_neo)** (da EleutherAI) rilasciato nel repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) da Sid Black, Stella Biderman, Leo Gao, Phil Wang e Connor Leahy.
+1. **[GPT NeoX](model_doc/gpt_neox)** (da EleutherAI) rilasciato con il paper [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://arxiv.org/abs/2204.06745) da Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach
+1. **[Hubert](model_doc/hubert)** (da Facebook) rilasciato con il paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) da Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
+1. **[I-BERT](model_doc/ibert)** (da Berkeley) rilasciato con il paper [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) da Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
+1. **[ImageGPT](model_doc/imagegpt)** (da OpenAI) rilasciato con il paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) da Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
+1. **[LayoutLM](model_doc/layoutlm)** (da Microsoft Research Asia) rilasciato con il paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318) da Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
+1. **[LayoutLMv2](model_doc/layoutlmv2)** (da Microsoft Research Asia) rilasciato con il paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) da Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
+1. **[LayoutLMv3](model_doc/layoutlmv3)** (da Microsoft Research Asia) rilasciato con il paper [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://arxiv.org/abs/2204.08387) da Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
+1. **[LayoutXLM](model_doc/layoutlxlm)** (da Microsoft Research Asia) rilasciato con il paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) da Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
+1. **[LED](model_doc/led)** (da AllenAI) rilasciato con il paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) da Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[Longformer](model_doc/longformer)** (da AllenAI) rilasciato con il paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) da Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LUKE](model_doc/luke)** (da Studio Ousia) rilasciato con il paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) da Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
+1. **[mLUKE](model_doc/mluke)** (da Studio Ousia) rilasciato con il paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) da Ryokan Ri, Ikuya Yamada, e Yoshimasa Tsuruoka.
+1. **[LXMERT](model_doc/lxmert)** (da UNC Chapel Hill) rilasciato con il paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490) da Hao Tan e Mohit Bansal.
+1. **[M2M100](model_doc/m2m_100)** (da Facebook) rilasciato con il paper [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) da Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+1. **[MarianMT](model_doc/marian)** Modello di machine learning per le traduzioni allenato utilizzando i dati [OPUS](http://opus.nlpl.eu/) di Jörg Tiedemann. Il [Framework Marian](https://marian-nmt.github.io/) è stato sviluppato dal Microsoft Translator Team.
+1. **[Mask2Former](model_doc/mask2former)** (da FAIR e UIUC) rilasciato con il paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) da Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
+1. **[MaskFormer](model_doc/maskformer)** (da Meta e UIUC) rilasciato con il paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) da Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
+1. **[MBart](model_doc/mbart)** (da Facebook) rilasciato con il paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) da Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+1. **[MBart-50](model_doc/mbart)** (da Facebook) rilasciato con il paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) da Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
+1. **[Megatron-BERT](model_doc/megatron-bert)** (da NVIDIA) rilasciato con il paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) da Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper e Bryan Catanzaro.
+1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (da NVIDIA) rilasciato con il paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) da Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper e Bryan Catanzaro.
+1. **[MPNet](model_doc/mpnet)** (da Microsoft Research) rilasciato con il paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) da Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+1. **[MT5](model_doc/mt5)** (da Google AI) rilasciato con il paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) da Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
+1. **[Nyströmformer](model_doc/nystromformer)** (dalla Università del Wisconsin - Madison) rilasciato con il paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902) da Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
+1. **[OneFormer](model_doc/oneformer)** (da SHI Labs) rilasciato con il paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) da Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
+1. **[OPT](master/model_doc/opt)** (da Meta AI) rilasciato con il paper [OPT: Open Pre-trained Transformer Language Models](https://arxiv.org/abs/2205.01068) da Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al.
+1. **[Pegasus](model_doc/pegasus)** (da Google) rilasciato con il paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777) da Jingqing Zhang, Yao Zhao, Mohammad Saleh e Peter J. Liu.
+1. **[Perceiver IO](model_doc/perceiver)** (da Deepmind) rilasciato con il paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795) da Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+1. **[PhoBERT](model_doc/phobert)** (da VinAI Research) rilasciato con il paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) da Dat Quoc Nguyen e Anh Tuan Nguyen.
+1. **[PLBart](model_doc/plbart)** (da UCLA NLP) rilasciato con il paper [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) da Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+1. **[PoolFormer](model_doc/poolformer)** (da Sea AI Labs) rilasciato con il paper [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) da Yu, Weihao e Luo, Mi e Zhou, Pan e Si, Chenyang e Zhou, Yichen e Wang, Xinchao e Feng, Jiashi e Yan, Shuicheng.
+1. **[ProphetNet](model_doc/prophetnet)** (da Microsoft Research) rilasciato con il paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) da Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang e Ming Zhou.
+1. **[QDQBert](model_doc/qdqbert)** (da NVIDIA) rilasciato con il paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602) da Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev e Paulius Micikevicius.
+1. **[REALM](model_doc/realm.html)** (da Google Research) rilasciato con il paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) da Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat e Ming-Wei Chang.
+1. **[Reformer](model_doc/reformer)** (da Google Research) rilasciato con il paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451) da Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+1. **[RemBERT](model_doc/rembert)** (da Google Research) rilasciato con il paper [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821) da Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
+1. **[RegNet](model_doc/regnet)** (da META Platforms) rilasciato con il paper [Designing Network Design Space](https://arxiv.org/abs/2003.13678) da Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+1. **[ResNet](model_doc/resnet)** (da Microsoft Research) rilasciato con il paper [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) da Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
+1. **[RoBERTa](model_doc/roberta)** (da Facebook), rilasciato assieme al paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) da Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
+1. **[RoFormer](model_doc/roformer)** (da ZhuiyiTechnology), rilasciato assieme al paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864) da Jianlin Su e Yu Lu e Shengfeng Pan e Bo Wen e Yunfeng Liu.
+1. **[SegFormer](model_doc/segformer)** (da NVIDIA) rilasciato con il paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) da Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
+1. **[SEW](model_doc/sew)** (da ASAPP) rilasciato con il paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) da Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SEW-D](model_doc/sew_d)** (da ASAPP) rilasciato con il paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) da Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (da Facebook), rilasciato assieme al paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) da Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
+1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (da Facebook), rilasciato assieme al paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) da Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+1. **[Splinter](model_doc/splinter)** (dalla Università di Tel Aviv), rilasciato assieme al paper [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) da Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
+1. **[SqueezeBert](model_doc/squeezebert)** (da Berkeley) rilasciato con il paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) da Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, e Kurt W. Keutzer.
+1. **[Swin Transformer](model_doc/swin)** (da Microsoft) rilasciato con il paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030) da Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+1. **[T5](model_doc/t5)** (da Google AI) rilasciato con il paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) da Colin Raffel e Noam Shazeer e Adam Roberts e Katherine Lee e Sharan Narang e Michael Matena e Yanqi Zhou e Wei Li e Peter J. Liu.
+1. **[T5v1.1](model_doc/t5v1.1)** (da Google AI) rilasciato nel repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) da Colin Raffel e Noam Shazeer e Adam Roberts e Katherine Lee e Sharan Narang e Michael Matena e Yanqi Zhou e Wei Li e Peter J. Liu.
+1. **[TAPAS](model_doc/tapas)** (da Google AI) rilasciato con il paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349) da Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno e Julian Martin Eisenschlos.
+1. **[TAPEX](model_doc/tapex)** (da Microsoft Research) rilasciato con il paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) da Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
+1. **[Trajectory Transformer](model_doc/trajectory_transformers)** (dall'Università della California a Berkeley) rilasciato con il paper [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://arxiv.org/abs/2106.02039) da Michael Janner, Qiyang Li, Sergey Levine
+1. **[Transformer-XL](model_doc/transfo-xl)** (da Google/CMU) rilasciato con il paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) da Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
+1. **[TrOCR](model_doc/trocr)** (da Microsoft), rilasciato assieme al paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) da Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
+1. **[UniSpeech](model_doc/unispeech)** (da Microsoft Research) rilasciato con il paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) da Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
+1. **[UniSpeechSat](model_doc/unispeech-sat)** (da Microsoft Research) rilasciato con il paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752) da Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
+1. **[VAN](model_doc/van)** (dalle Università di Tsinghua e Nankai) rilasciato con il paper [Visual Attention Network](https://arxiv.org/abs/2202.09741) da Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+1. **[ViLT](model_doc/vilt)** (da NAVER AI Lab/Kakao Enterprise/Kakao Brain) rilasciato con il paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334) da Wonjae Kim, Bokyung Son, Ildoo Kim.
+1. **[Vision Transformer (ViT)](model_doc/vit)** (da Google AI) rilasciato con il paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) da Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[ViTMAE](model_doc/vit_mae)** (da Meta AI) rilasciato con il paper [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377) da Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
+1. **[VisualBERT](model_doc/visual_bert)** (da UCLA NLP) rilasciato con il paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557) da Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
+1. **[WavLM](model_doc/wavlm)** (da Microsoft Research) rilasciato con il paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900) da Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
+1. **[Wav2Vec2](model_doc/wav2vec2)** (da Facebook AI) rilasciato con il paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477) da Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
+1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (da Facebook AI) rilasciato con il paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680) da Qiantong Xu, Alexei Baevski, Michael Auli.
+1. **[XGLM](model_doc/xglm)** (da Facebook AI) rilasciato con il paper [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668) da Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
+1. **[XLM](model_doc/xlm)** (v Facebook) rilasciato assieme al paper [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291) da Guillaume Lample e Alexis Conneau.
+1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (da Microsoft Research) rilasciato con il paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) da Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang e Ming Zhou.
+1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (da Facebook AI), rilasciato assieme al paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) da Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer e Veselin Stoyanov.
+1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (da Facebook AI), rilasciato assieme al paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572) da Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
+1. **[XLNet](model_doc/xlnet)** (da Google/CMU) rilasciato con il paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237) da Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
+1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (da Facebook AI) rilasciato con il paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979) da Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
+1. **[XLS-R](model_doc/xls_r)** (da Facebook AI) rilasciato con il paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296) da Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
+1. **[YOLOS](model_doc/yolos)** (dalla Università della scienza e tecnologia di Huazhong) rilasciato con il paper [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://arxiv.org/abs/2106.00666) da Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu.
+1. **[YOSO](model_doc/yoso)** (dall'Università del Wisconsin - Madison) rilasciato con il paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714) da Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
+
+
+### Framework supportati
+
+La tabella seguente rappresenta il supporto attuale nella libreria per ognuno di questi modelli, si può identificare se questi hanno un Python
+tokenizer (chiamato "slow"). Un tokenizer "fast" supportato dalla libreria 🤗 Tokenizers, e se hanno supporto in Jax (via Flax), PyTorch, e/o TensorFlow.
+
+
+
+| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:---------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBirdPegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Canine | ✅ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNext | ❌ | ❌ | ✅ | ✅ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| CvT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Flava | ❌ | ❌ | ✅ | ❌ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LayoutLMv3 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MegatronBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| mT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Nystromformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| OPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Realm | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| SegFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Swin | ❌ | ❌ | ✅ | ✅ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| VisualBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ❌ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLMProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/installation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/installation.md
new file mode 100644
index 0000000000000000000000000000000000000000..a4f444c1eb0c4cbb71218c7a7f66ffe7ff230456
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/installation.md
@@ -0,0 +1,239 @@
+
+
+# Installazione
+
+Installa 🤗 Transformers per qualsiasi libreria di deep learning con cui stai lavorando, imposta la tua cache, e opzionalmente configura 🤗 Transformers per l'esecuzione offline.
+
+🤗 Transformers è testato su Python 3.6+, PyTorch 1.1.0+, TensorFlow 2.0+, e Flax. Segui le istruzioni di installazione seguenti per la libreria di deep learning che stai utilizzando:
+
+* [PyTorch](https://pytorch.org/get-started/locally/) istruzioni di installazione.
+* [TensorFlow 2.0](https://www.tensorflow.org/install/pip) istruzioni di installazione.
+* [Flax](https://flax.readthedocs.io/en/latest/) istruzioni di installazione.
+
+## Installazione con pip
+
+Puoi installare 🤗 Transformers in un [ambiente virtuale](https://docs.python.org/3/library/venv.html). Se non sei familiare con gli ambienti virtuali in Python, dai un'occhiata a questa [guida](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/). Un ambiente virtuale rende più semplice la gestione di progetti differenti, evitando problemi di compatibilità tra dipendenze.
+
+Inizia creando un ambiente virtuale nella directory del tuo progetto:
+
+```bash
+python -m venv .env
+```
+
+Attiva l'ambiente virtuale:
+
+```bash
+source .env/bin/activate
+```
+
+Ora puoi procedere con l'installazione di 🤗 Transformers eseguendo il comando seguente:
+
+```bash
+pip install transformers
+```
+
+Per il solo supporto della CPU, puoi installare facilmente 🤗 Transformers e una libreria di deep learning in solo una riga. Ad esempio, installiamo 🤗 Transformers e PyTorch con:
+
+```bash
+pip install transformers[torch]
+```
+
+🤗 Transformers e TensorFlow 2.0:
+
+```bash
+pip install transformers[tf-cpu]
+```
+
+🤗 Transformers e Flax:
+
+```bash
+pip install transformers[flax]
+```
+
+Infine, verifica se 🤗 Transformers è stato installato in modo appropriato eseguendo il seguente comando. Questo scaricherà un modello pre-allenato:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('we love you'))"
+```
+
+Dopodiché stampa l'etichetta e il punteggio:
+
+```bash
+[{'label': 'POSITIVE', 'score': 0.9998704791069031}]
+```
+
+## Installazione dalla fonte
+
+Installa 🤗 Transformers dalla fonte con il seguente comando:
+
+```bash
+pip install git+https://github.com/huggingface/transformers
+```
+
+Questo comando installa la versione `main` più attuale invece dell'ultima versione stabile. Questo è utile per stare al passo con gli ultimi sviluppi. Ad esempio, se un bug è stato sistemato da quando è uscita l'ultima versione ufficiale ma non è stata ancora rilasciata una nuova versione. Tuttavia, questo significa che questa versione `main` può non essere sempre stabile. Ci sforziamo per mantenere la versione `main` operativa, e la maggior parte dei problemi viene risolta in poche ore o in un giorno. Se riscontri un problema, per favore apri una [Issue](https://github.com/huggingface/transformers/issues) così possiamo sistemarlo ancora più velocemente!
+
+Controlla se 🤗 Transformers è stata installata in modo appropriato con il seguente comando:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('I love you'))"
+```
+
+## Installazione modificabile
+
+Hai bisogno di un'installazione modificabile se vuoi:
+
+* Usare la versione `main` del codice dalla fonte.
+* Contribuire a 🤗 Transformers e hai bisogno di testare i cambiamenti nel codice.
+
+Clona il repository e installa 🤗 Transformers con i seguenti comandi:
+
+```bash
+git clone https://github.com/huggingface/transformers.git
+cd transformers
+pip install -e .
+```
+
+Questi comandi collegheranno la cartella in cui è stato clonato il repository e i path delle librerie Python. Python guarderà ora all'interno della cartella clonata, oltre ai normali path delle librerie. Per esempio, se i tuoi pacchetti Python sono installati tipicamente in `~/anaconda3/envs/main/lib/python3.7/site-packages/`, Python cercherà anche nella cartella clonata: `~/transformers/`.
+
+
+
+Devi tenere la cartella `transformers` se vuoi continuare ad utilizzare la libreria.
+
+
+
+Ora puoi facilmente aggiornare il tuo clone all'ultima versione di 🤗 Transformers con il seguente comando:
+
+```bash
+cd ~/transformers/
+git pull
+```
+
+Il tuo ambiente Python troverà la versione `main` di 🤗 Transformers alla prossima esecuzione.
+
+## Installazione con conda
+
+Installazione dal canale conda `conda-forge`:
+
+```bash
+conda install conda-forge::transformers
+```
+
+## Impostazione della cache
+
+I modelli pre-allenati sono scaricati e memorizzati localmente nella cache in: `~/.cache/huggingface/transformers/`. Questa è la directory di default data dalla variabile d'ambiente della shell `TRANSFORMERS_CACHE`. Su Windows, la directory di default è data da `C:\Users\username\.cache\huggingface\transformers`. Puoi cambiare le variabili d'ambiente della shell indicate in seguito, in ordine di priorità, per specificare una directory differente per la cache:
+
+1. Variabile d'ambiente della shell (default): `TRANSFORMERS_CACHE`.
+2. Variabile d'ambiente della shell: `HF_HOME` + `transformers/`.
+3. Variabile d'ambiente della shell: `XDG_CACHE_HOME` + `/huggingface/transformers`.
+
+
+
+🤗 Transformers utilizzerà le variabili d'ambiente della shell `PYTORCH_TRANSFORMERS_CACHE` o `PYTORCH_PRETRAINED_BERT_CACHE` se si proviene da un'iterazione precedente di questa libreria e sono state impostate queste variabili d'ambiente, a meno che non si specifichi la variabile d'ambiente della shell `TRANSFORMERS_CACHE`.
+
+
+
+## Modalità Offline
+
+🤗 Transformers può essere eseguita in un ambiente firewalled o offline utilizzando solo file locali. Imposta la variabile d'ambiente `HF_HUB_OFFLINE=1` per abilitare questo comportamento.
+
+
+
+Aggiungi [🤗 Datasets](https://huggingface.co/docs/datasets/) al tuo flusso di lavoro offline di training impostando la variabile d'ambiente `HF_DATASETS_OFFLINE=1`.
+
+
+
+Ad esempio, in genere si esegue un programma su una rete normale, protetta da firewall per le istanze esterne, con il seguente comando:
+
+```bash
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+Esegui lo stesso programma in un'istanza offline con:
+
+```bash
+HF_DATASETS_OFFLINE=1 HF_HUB_OFFLINE=1 \
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+Lo script viene ora eseguito senza bloccarsi o attendere il timeout, perché sa di dover cercare solo file locali.
+
+### Ottenere modelli e tokenizer per l'uso offline
+
+Un'altra opzione per utilizzare offline 🤗 Transformers è scaricare i file in anticipo, e poi puntare al loro path locale quando hai la necessità di utilizzarli offline. Ci sono tre modi per fare questo:
+
+* Scarica un file tramite l'interfaccia utente sul [Model Hub](https://huggingface.co/models) premendo sull'icona ↓.
+
+ 
+
+* Utilizza il flusso [`PreTrainedModel.from_pretrained`] e [`PreTrainedModel.save_pretrained`]:
+
+ 1. Scarica i tuoi file in anticipo con [`PreTrainedModel.from_pretrained`]:
+
+ ```py
+ >>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("bigscience/T0_3B")
+ >>> model = AutoModelForSeq2SeqLM.from_pretrained("bigscience/T0_3B")
+ ```
+
+ 2. Salva i tuoi file in una directory specificata con [`PreTrainedModel.save_pretrained`]:
+
+ ```py
+ >>> tokenizer.save_pretrained("./il/tuo/path/bigscience_t0")
+ >>> model.save_pretrained("./il/tuo/path/bigscience_t0")
+ ```
+
+ 3. Ora quando sei offline, carica i tuoi file con [`PreTrainedModel.from_pretrained`] dalla directory specificata:
+
+ ```py
+ >>> tokenizer = AutoTokenizer.from_pretrained("./il/tuo/path/bigscience_t0")
+ >>> model = AutoModel.from_pretrained("./il/tuo/path/bigscience_t0")
+ ```
+
+* Scarica in maniera programmatica i file con la libreria [huggingface_hub](https://github.com/huggingface/huggingface_hub/tree/main/src/huggingface_hub):
+
+ 1. Installa la libreria `huggingface_hub` nel tuo ambiente virtuale:
+
+ ```bash
+ python -m pip install huggingface_hub
+ ```
+
+ 2. Utilizza la funzione [`hf_hub_download`](https://huggingface.co/docs/hub/adding-a-library#download-files-from-the-hub) per scaricare un file in un path specifico. Per esempio, il seguente comando scarica il file `config.json` dal modello [T0](https://huggingface.co/bigscience/T0_3B) nel path che desideri:
+
+ ```py
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> hf_hub_download(repo_id="bigscience/T0_3B", filename="config.json", cache_dir="./il/tuo/path/bigscience_t0")
+ ```
+
+Una volta che il tuo file è scaricato e salvato in cache localmente, specifica il suo path locale per caricarlo e utilizzarlo:
+
+```py
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("./il/tuo/path/bigscience_t0/config.json")
+```
+
+
+
+Fai riferimento alla sezione [How to download files from the Hub](https://huggingface.co/docs/hub/how-to-downstream) per avere maggiori dettagli su come scaricare modelli presenti sull Hub.
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/migration.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/migration.md
new file mode 100644
index 0000000000000000000000000000000000000000..07d31705784e7fa626a9aadf011aaf5a88e96e09
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/migration.md
@@ -0,0 +1,313 @@
+
+
+# Migrazione da pacchetti precedenti
+
+## Migrazione da transformers `v3.x` a `v4.x`
+
+Un paio di modifiche sono state introdotte nel passaggio dalla versione 3 alla versione 4. Di seguito è riportato un riepilogo delle
+modifiche previste:
+
+#### 1. AutoTokenizer e pipeline ora utilizzano tokenizer veloci (rust) per impostazione predefinita.
+
+I tokenizer python e rust hanno all'incirca le stesse API, ma i tokenizer rust hanno un set di funzionalità più completo.
+
+Ciò introduce due modifiche sostanziali:
+- La gestione dei token in overflow tra i tokenizer Python e Rust è diversa.
+- I tokenizers di rust non accettano numeri interi nei metodi di codifica.
+
+##### Come ottenere lo stesso comportamento di v3.x in v4.x
+
+- Le pipeline ora contengono funzionalità aggiuntive pronte all'uso. Vedi la [pipeline di classificazione dei token con il flag `grouped_entities`](main_classes/pipelines#transformers.TokenClassificationPipeline).
+- Gli auto-tokenizer ora restituiscono tokenizer rust. Per ottenere invece i tokenizer python, l'utente deve usare il flag `use_fast` impostandolo `False`:
+
+Nella versione `v3.x`:
+```py
+from transformers import AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
+```
+per ottenere lo stesso nella versione `v4.x`:
+```py
+from transformers import AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased", use_fast=False)
+```
+
+#### 2. SentencePiece è stato rimosso dalle dipendenze richieste
+
+Il requisito sulla dipendenza SentencePiece è stato rimosso da `setup.py`. È stato fatto per avere un canale su anaconda cloud senza basarsi su `conda-forge`. Ciò significa che i tokenizer che dipendono dalla libreria SentencePiece non saranno disponibili con un'installazione standard di `transformers`.
+
+Ciò include le versioni **lente** di:
+- `XLNetTokenizer`
+- `AlbertTokenizer`
+- `CamembertTokenizer`
+- `MBartTokenizer`
+- `PegasusTokenizer`
+- `T5Tokenizer`
+- `ReformerTokenizer`
+- `XLMRobertaTokenizer`
+
+##### Come ottenere lo stesso comportamento della v3.x nella v4.x
+
+Per ottenere lo stesso comportamento della versione `v3.x`, devi installare anche `sentencepiece`:
+
+Nella versione `v3.x`:
+```bash
+pip install transformers
+```
+per ottenere lo stesso nella versione `v4.x`:
+```bash
+pip install transformers[sentencepiece]
+```
+o
+```bash
+pip install transformers stentencepiece
+```
+#### 3. L'architettura delle repo è stato aggiornata in modo che ogni modello abbia la propria cartella
+
+Con l’aggiunta di nuovi modelli, il numero di file nella cartella `src/transformers` continua a crescere e diventa più difficile navigare e capire. Abbiamo fatto la scelta di inserire ogni modello e i file che lo accompagnano nelle proprie sottocartelle.
+
+Si tratta di una modifica sostanziale in quanto l'importazione di layer intermedi utilizzando direttamente il modulo di un modello deve essere eseguita tramite un percorso diverso.
+
+##### Come ottenere lo stesso comportamento della v3.x nella v4.x
+
+Per ottenere lo stesso comportamento della versione `v3.x`, devi aggiornare il percorso utilizzato per accedere ai layer.
+
+Nella versione `v3.x`:
+```bash
+from transformers.modeling_bert import BertLayer
+```
+per ottenere lo stesso nella versione `v4.x`:
+```bash
+from transformers.models.bert.modeling_bert import BertLayer
+```
+
+#### 4. Impostare l'argomento `return_dict` su `True` per impostazione predefinita
+
+L'[argomento `return_dict`](main_classes/output) abilita la restituzione di oggetti python dict-like contenenti gli output del modello, invece delle tuple standard. Questo oggetto è self-documented poiché le chiavi possono essere utilizzate per recuperare valori, comportandosi anche come una tupla e gli utenti possono recuperare oggetti per indexing o slicing.
+
+Questa è una modifica sostanziale poiché la tupla non può essere decompressa: `value0, value1 = outputs` non funzionerà.
+
+##### Come ottenere lo stesso comportamento della v3.x nella v4.x
+
+Per ottenere lo stesso comportamento della versione `v3.x`, specifica l'argomento `return_dict` come `False`, sia nella configurazione del modello che nel passaggio successivo.
+
+Nella versione `v3.x`:
+```bash
+model = BertModel.from_pretrained("google-bert/bert-base-cased")
+outputs = model(**inputs)
+```
+per ottenere lo stesso nella versione `v4.x`:
+```bash
+model = BertModel.from_pretrained("google-bert/bert-base-cased")
+outputs = model(**inputs, return_dict=False)
+```
+o
+```bash
+model = BertModel.from_pretrained("google-bert/bert-base-cased", return_dict=False)
+outputs = model(**inputs)
+```
+
+#### 5. Rimozione di alcuni attributi deprecati
+
+Gli attributi sono stati rimossi se deprecati da almeno un mese. L'elenco completo degli attributi obsoleti è disponibile in [#8604](https://github.com/huggingface/transformers/pull/8604).
+
+Ecco un elenco di questi attributi/metodi/argomenti e quali dovrebbero essere le loro sostituzioni:
+
+In diversi modelli, le etichette diventano coerenti con gli altri modelli:
+- `masked_lm_labels` diventa `labels` in `AlbertForMaskedLM` e `AlbertForPreTraining`.
+- `masked_lm_labels` diventa `labels` in `BertForMaskedLM` e `BertForPreTraining`.
+- `masked_lm_labels` diventa `labels` in `DistilBertForMaskedLM`.
+- `masked_lm_labels` diventa `labels` in `ElectraForMaskedLM`.
+- `masked_lm_labels` diventa `labels` in `LongformerForMaskedLM`.
+- `masked_lm_labels` diventa `labels` in `MobileBertForMaskedLM`.
+- `masked_lm_labels` diventa `labels` in `RobertaForMaskedLM`.
+- `lm_labels` diventa `labels` in `BartForConditionalGeneration`.
+- `lm_labels` diventa `labels` in `GPT2DoubleHeadsModel`.
+- `lm_labels` diventa `labels` in `OpenAIGPTDoubleHeadsModel`.
+- `lm_labels` diventa `labels` in `T5ForConditionalGeneration`.
+
+In diversi modelli, il meccanismo di memorizzazione nella cache diventa coerente con gli altri:
+- `decoder_cached_states` diventa `past_key_values` in tutti i modelli BART-like, FSMT e T5.
+- `decoder_past_key_values` diventa `past_key_values` in tutti i modelli BART-like, FSMT e T5.
+- `past` diventa `past_key_values` in tutti i modelli CTRL.
+- `past` diventa `past_key_values` in tutti i modelli GPT-2.
+
+Per quanto riguarda le classi tokenizer:
+- L'attributo tokenizer `max_len` diventa `model_max_length`.
+- L'attributo tokenizer `return_lengths` diventa `return_length`.
+- L'argomento di codifica del tokenizer `is_pretokenized` diventa `is_split_into_words`.
+
+Per quanto riguarda la classe `Trainer`:
+- L'argomento `tb_writer` di `Trainer` è stato rimosso in favore della funzione richiamabile `TensorBoardCallback(tb_writer=...)`.
+- L'argomento `prediction_loss_only` di `Trainer` è stato rimosso in favore dell'argomento di classe `args.prediction_loss_only`.
+- L'attributo `data_collator` di `Trainer` sarà richiamabile.
+- Il metodo `_log` di `Trainer` è deprecato a favore di `log`.
+- Il metodo `_training_step` di `Trainer` è deprecato a favore di `training_step`.
+- Il metodo `_prediction_loop` di `Trainer` è deprecato a favore di `prediction_loop`.
+- Il metodo `is_local_master` di `Trainer` è deprecato a favore di `is_local_process_zero`.
+- Il metodo `is_world_master` di `Trainer` è deprecato a favore di `is_world_process_zero`.
+
+Per quanto riguarda la classe `TrainingArguments`:
+- L'argomento `evaluate_during_training` di `TrainingArguments` è deprecato a favore di `eval_strategy`.
+
+Per quanto riguarda il modello Transfo-XL:
+- L'attributo di configurazione `tie_weight` di Transfo-XL diventa `tie_words_embeddings`.
+- Il metodo di modellazione `reset_length` di Transfo-XL diventa `reset_memory_length`.
+
+Per quanto riguarda le pipeline:
+- L'argomento `topk` di `FillMaskPipeline` diventa `top_k`.
+
+
+
+## Passaggio da pytorch-transformers a 🤗 Transformers
+
+Ecco un breve riepilogo di ciò a cui prestare attenzione durante il passaggio da `pytorch-transformers` a 🤗 Transformers.
+
+### L’ordine posizionale di alcune parole chiave di input dei modelli (`attention_mask`, `token_type_ids`...) è cambiato
+
+Per usare Torchscript (vedi #1010, #1204 e #1195) l'ordine specifico delle **parole chiave di input** di alcuni modelli (`attention_mask`, `token_type_ids`...) è stato modificato.
+
+Se inizializzavi i modelli usando parole chiave per gli argomenti, ad esempio `model(inputs_ids, attention_mask=attention_mask, token_type_ids=token_type_ids)`, questo non dovrebbe causare alcun cambiamento.
+
+Se inizializzavi i modelli con input posizionali per gli argomenti, ad esempio `model(inputs_ids, attention_mask, token_type_ids)`, potrebbe essere necessario ricontrollare l'ordine esatto degli argomenti di input.
+
+## Migrazione da pytorch-pretrained-bert
+
+Ecco un breve riepilogo di ciò a cui prestare attenzione durante la migrazione da `pytorch-pretrained-bert` a 🤗 Transformers
+
+### I modelli restituiscono sempre `tuple`
+
+La principale modifica di rilievo durante la migrazione da `pytorch-pretrained-bert` a 🤗 Transformers è che il metodo dei modelli di previsione dà sempre una `tupla` con vari elementi a seconda del modello e dei parametri di configurazione.
+
+Il contenuto esatto delle tuple per ciascun modello è mostrato in dettaglio nelle docstring dei modelli e nella [documentazione](https://huggingface.co/transformers/).
+
+In quasi tutti i casi, andrà bene prendendo il primo elemento dell'output come quello che avresti precedentemente utilizzato in `pytorch-pretrained-bert`.
+
+Ecco un esempio di conversione da `pytorch-pretrained-bert`
+ a 🤗 Transformers per un modello di classificazione `BertForSequenceClassification`:
+
+```python
+# Carichiamo il nostro modello
+model = BertForSequenceClassification.from_pretrained("google-bert/bert-base-uncased")
+
+# Se usavi questa riga in pytorch-pretrained-bert :
+loss = model(input_ids, labels=labels)
+
+# Ora usa questa riga in 🤗 Transformers per estrarre la perdita dalla tupla di output:
+outputs = model(input_ids, labels=labels)
+loss = outputs[0]
+
+# In 🤗 Transformers puoi anche avere accesso ai logit:
+loss, logits = outputs[:2]
+
+# Ed anche agli attention weight se configuri il modello per restituirli (e anche altri output, vedi le docstring e la documentazione)
+model = BertForSequenceClassification.from_pretrained(" google-bert/bert-base-uncased", output_attentions=True)
+outputs = model(input_ids, labels=labels)
+loss, logits, attentions = outputs
+```
+
+### Serializzazione
+
+Modifica sostanziale nel metodo `from_pretrained()`:
+
+1. I modelli sono ora impostati in modalità di valutazione in maniera predefinita quando usi il metodo `from_pretrained()`. Per addestrarli non dimenticare di riportarli in modalità di addestramento (`model.train()`) per attivare i moduli di dropout.
+
+2. Gli argomenti aggiuntivi `*inputs` e `**kwargs` forniti al metodo `from_pretrained()` venivano passati direttamente al metodo `__init__()` della classe sottostante del modello. Ora sono usati per aggiornare prima l'attributo di configurazione del modello, che può non funzionare con le classi del modello derivate costruite basandosi sui precedenti esempi di `BertForSequenceClassification`. Più precisamente, gli argomenti posizionali `*inputs` forniti a `from_pretrained()` vengono inoltrati direttamente al metodo `__init__()` del modello mentre gli argomenti keyword `**kwargs` (i) che corrispondono agli attributi della classe di configurazione, vengono utilizzati per aggiornare tali attributi (ii) che non corrispondono ad alcun attributo della classe di configurazione, vengono inoltrati al metodo `__init__()`.
+
+Inoltre, sebbene non si tratti di una modifica sostanziale, i metodi di serializzazione sono stati standardizzati e probabilmente dovresti passare al nuovo metodo `save_pretrained(save_directory)` se prima usavi qualsiasi altro metodo di serializzazione.
+
+Ecco un esempio:
+
+```python
+### Carichiamo un modello e un tokenizer
+model = BertForSequenceClassification.from_pretrained("google-bert/bert-base-uncased")
+tokenizer = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+
+### Facciamo fare alcune cose al nostro modello e tokenizer
+# Es: aggiungiamo nuovi token al vocabolario e agli embending del nostro modello
+tokenizer.add_tokens(["[SPECIAL_TOKEN_1]", "[SPECIAL_TOKEN_2]"])
+model.resize_token_embeddings(len(tokenizer))
+# Alleniamo il nostro modello
+train(model)
+
+### Ora salviamo il nostro modello e il tokenizer in una cartella
+model.save_pretrained("./my_saved_model_directory/")
+tokenizer.save_pretrained("./my_saved_model_directory/")
+
+### Ricarichiamo il modello e il tokenizer
+model = BertForSequenceClassification.from_pretrained("./my_saved_model_directory/")
+tokenizer = BertTokenizer.from_pretrained("./my_saved_model_directory/")
+```
+
+### Ottimizzatori: BertAdam e OpenAIAdam ora sono AdamW, lo scheduling è quello standard PyTorch
+
+I due ottimizzatori precedenti inclusi, `BertAdam` e `OpenAIAdam`, sono stati sostituiti da un singolo `AdamW` che presenta alcune differenze:
+
+- implementa solo la correzione del weights decay,
+- lo scheduling ora è esterno (vedi sotto),
+- anche il gradient clipping ora è esterno (vedi sotto).
+
+Il nuovo ottimizzatore `AdamW` corrisponde alle API di `Adam` di PyTorch e ti consente di utilizzare metodi PyTorch o apex per lo scheduling e il clipping.
+
+Lo scheduling è ora standard [PyTorch learning rate schedulers](https://pytorch.org/docs/stable/optim.html#how-to-adjust-learning-rate) e non fanno più parte dell'ottimizzatore.
+
+Ecco un esempio di linear warmup e decay con `BertAdam` e con `AdamW`:
+
+```python
+# Parametri:
+lr = 1e-3
+max_grad_norm = 1.0
+num_training_steps = 1000
+num_warmup_steps = 100
+warmup_proportion = float( num_warmup_steps) / float(num_training_steps) # 0.1
+
+### In precedenza l'ottimizzatore BertAdam veniva istanziato in questo modo:
+optimizer = BertAdam(
+ model.parameters(),
+ lr=lr,
+ schedule="warmup_linear",
+ warmup=warmup_proportion,
+ num_training_steps=num_training_steps,
+)
+### e usato in questo modo:
+for batch in train_data:
+ loss = model(batch)
+ loss.backward()
+ optimizer.step()
+
+### In 🤗 Transformers, ottimizzatore e schedule sono divisi e usati in questo modo:
+optimizer = AdamW(
+ model.parameters(), lr=lr, correct_bias=False
+) # Per riprodurre il comportamento specifico di BertAdam impostare correct_bias=False
+scheduler = get_linear_schedule_with_warmup(
+ optimizer, num_warmup_steps=num_warmup_steps, num_training_steps=num_training_steps
+) # PyTorch scheduler
+### e va usato così:
+for batch in train_data:
+ loss = model(batch)
+ loss.backward()
+ torch.nn.utils.clip_grad_norm_(
+ model.parameters(), max_grad_norm
+ ) # Gradient clipping non è più in AdamW (quindi puoi usare amp senza problemi)
+ optimizer.step()
+ scheduler.step()
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/model_sharing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/model_sharing.md
new file mode 100644
index 0000000000000000000000000000000000000000..6505658616baa568de39dd63324803d6c5a00bbe
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/model_sharing.md
@@ -0,0 +1,238 @@
+
+
+# Condividi un modello
+
+Gli ultimi due tutorial ti hanno mostrato come puoi fare fine-tuning di un modello con PyTorch, Keras e 🤗 Accelerate per configurazioni distribuite. Il prossimo passo è quello di condividere il tuo modello con la community! In Hugging Face, crediamo nella condivisione della conoscenza e delle risorse in modo da democratizzare l'intelligenza artificiale per chiunque. Ti incoraggiamo a considerare di condividere il tuo modello con la community per aiutare altre persone a risparmiare tempo e risorse.
+
+In questo tutorial, imparerai due metodi per la condivisione di un modello trained o fine-tuned nel [Model Hub](https://huggingface.co/models):
+
+- Condividi in modo programmatico i tuoi file nell'Hub.
+- Trascina i tuoi file nell'Hub mediante interfaccia grafica.
+
+VIDEO
+
+
+
+Per condividere un modello con la community, hai bisogno di un account su [huggingface.co](https://huggingface.co/join). Puoi anche unirti ad un'organizzazione esistente o crearne una nuova.
+
+
+
+## Caratteristiche dei repository
+
+Ogni repository nel Model Hub si comporta come un tipico repository di GitHub. I nostri repository offrono il versionamento, la cronologia dei commit, e la possibilità di visualizzare le differenze.
+
+Il versionamento all'interno del Model Hub è basato su git e [git-lfs](https://git-lfs.github.com/). In altre parole, puoi trattare un modello come un unico repository, consentendo un maggiore controllo degli accessi e maggiore scalabilità. Il controllo delle versioni consente *revisions*, un metodo per appuntare una versione specifica di un modello con un hash di commit, un tag o un branch.
+
+Come risultato, puoi caricare una specifica versione di un modello con il parametro `revision`:
+
+```py
+>>> model = AutoModel.from_pretrained(
+... "julien-c/EsperBERTo-small", revision="4c77982" # nome di un tag, di un branch, o commit hash
+... )
+```
+
+Anche i file possono essere modificati facilmente in un repository ed è possibile visualizzare la cronologia dei commit e le differenze:
+
+
+
+## Configurazione
+
+Prima di condividere un modello nell'Hub, hai bisogno delle tue credenziali di Hugging Face. Se hai accesso ad un terminale, esegui il seguente comando nell'ambiente virtuale in cui è installata la libreria 🤗 Transformers. Questo memorizzerà il tuo token di accesso nella cartella cache di Hugging Face (di default `~/.cache/`):
+
+```bash
+huggingface-cli login
+```
+
+Se stai usando un notebook come Jupyter o Colaboratory, assicurati di avere la libreria [`huggingface_hub`](https://huggingface.co/docs/hub/adding-a-library) installata. Questa libreria ti permette di interagire in maniera programmatica con l'Hub.
+
+```bash
+pip install huggingface_hub
+```
+
+Utilizza `notebook_login` per accedere all'Hub, e segui il link [qui](https://huggingface.co/settings/token) per generare un token con cui effettuare il login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Converti un modello per tutti i framework
+
+Per assicurarti che il tuo modello possa essere utilizzato da persone che lavorano con un framework differente, ti raccomandiamo di convertire e caricare il tuo modello sia con i checkpoint di PyTorch che con quelli di TensorFlow. Anche se è possibile caricare il modello da un framework diverso, se si salta questo passaggio, il caricamento sarà più lento perché 🤗 Transformers ha bisogno di convertire i checkpoint al momento.
+
+Convertire un checkpoint per un altro framework è semplice. Assicurati di avere PyTorch e TensorFlow installati (vedi [qui](installation) per le istruzioni d'installazione), e poi trova il modello specifico per il tuo compito nell'altro framework.
+
+
+
+Specifica `from_tf=True` per convertire un checkpoint da TensorFlow a PyTorch:
+
+```py
+>>> pt_model = DistilBertForSequenceClassification.from_pretrained(
+... "path/verso/il-nome-magnifico-che-hai-scelto", from_tf=True
+... )
+>>> pt_model.save_pretrained("path/verso/il-nome-magnifico-che-hai-scelto")
+```
+
+
+Specifica `from_pt=True` per convertire un checkpoint da PyTorch a TensorFlow:
+
+```py
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained(
+... "path/verso/il-nome-magnifico-che-hai-scelto", from_pt=True
+... )
+```
+
+Poi puoi salvare il tuo nuovo modello in TensorFlow con il suo nuovo checkpoint:
+
+```py
+>>> tf_model.save_pretrained("path/verso/il-nome-magnifico-che-hai-scelto")
+```
+
+
+Se un modello è disponibile in Flax, puoi anche convertire un checkpoint da PyTorch a Flax:
+
+```py
+>>> flax_model = FlaxDistilBertForSequenceClassification.from_pretrained(
+... "path/verso/il-nome-magnifico-che-hai-scelto", from_pt=True
+... )
+```
+
+
+
+## Condividi un modello durante il training
+
+
+
+
+
+Condividi un modello nell'Hub con [`PushToHubCallback`]. Nella funzione [`PushToHubCallback`], aggiungi:
+
+- Una directory di output per il tuo modello.
+- Un tokenizer.
+- L'`hub_model_id`, che è il tuo username sull'Hub e il nome del modello.
+
+```py
+>>> from transformers import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="./il_path_dove_salvare_il_tuo_modello",
+... tokenizer=tokenizer,
+... hub_model_id="il-tuo-username/il-mio-bellissimo-modello",
+... )
+```
+
+Aggiungi il callback a [`fit`](https://keras.io/api/models/model_training_apis/), e 🤗 Transformers caricherà il modello allenato nell'Hub:
+
+```py
+>>> model.fit(tf_train_dataset, validation_data=tf_validation_dataset, epochs=3, callbacks=push_to_hub_callback)
+```
+
+
+
+## Utilizzare la funzione `push_to_hub`
+
+Puoi anche chiamare `push_to_hub` direttamente sul tuo modello per caricarlo nell'Hub.
+
+Specifica il nome del tuo modello in `push_to_hub`:
+
+```py
+>>> pt_model.push_to_hub("il-mio-bellissimo-modello")
+```
+
+Questo crea un repository sotto il proprio username con il nome del modello `il-mio-bellissimo-modello`. Ora chiunque può caricare il tuo modello con la funzione `from_pretrained`:
+
+```py
+>>> from transformers import AutoModel
+
+>>> model = AutoModel.from_pretrained("il-tuo-username/il-mio-bellissimo-modello")
+```
+
+Se fai parte di un'organizzazione e vuoi invece condividere un modello sotto il nome dell'organizzazione, aggiungi il parametro `organization`:
+
+```py
+>>> pt_model.push_to_hub("il-mio-bellissimo-modello", organization="la-mia-fantastica-org")
+```
+
+La funzione `push_to_hub` può essere anche utilizzata per aggiungere altri file al repository del modello. Per esempio, aggiungi un tokenizer ad un repository di un modello:
+
+```py
+>>> tokenizer.push_to_hub("il-mio-bellissimo-modello")
+```
+
+O magari potresti voler aggiungere la versione di TensorFlow del tuo modello PyTorch a cui hai fatto fine-tuning:
+
+```py
+>>> tf_model.push_to_hub("il-mio-bellissimo-modello")
+```
+
+Ora quando navighi nel tuo profilo Hugging Face, dovresti vedere il tuo repository del modello appena creato. Premendo sulla scheda **Files** vengono visualizzati tutti i file caricati nel repository.
+
+Per maggiori dettagli su come creare e caricare file ad un repository, fai riferimento alla documentazione [qui](https://huggingface.co/docs/hub/how-to-upstream).
+
+## Carica un modello utilizzando l'interfaccia web
+
+Chi preferisce un approccio senza codice può caricare un modello tramite l'interfaccia web dell'hub. Visita [huggingface.co/new](https://huggingface.co/new) per creare un nuovo repository:
+
+
+
+Da qui, aggiungi alcune informazioni sul tuo modello:
+
+- Seleziona il/la **owner** del repository. Puoi essere te o qualunque organizzazione di cui fai parte.
+- Scegli un nome per il tuo modello, il quale sarà anche il nome del repository.
+- Scegli se il tuo modello è pubblico o privato.
+- Specifica la licenza utilizzata per il tuo modello.
+
+Ora premi sulla scheda **Files** e premi sul pulsante **Add file** per caricare un nuovo file al tuo repository. Trascina poi un file per caricarlo e aggiungere un messaggio di commit.
+
+
+
+## Aggiungi una scheda del modello
+
+Per assicurarti che chiunque possa comprendere le abilità, limitazioni, i potenziali bias e le considerazioni etiche del tuo modello, per favore aggiungi una scheda del modello (model card, in inglese) al tuo repository. La scheda del modello è definita nel file `README.md`. Puoi aggiungere una scheda del modello:
+
+* Creando manualmente e caricando un file `README.md`.
+* Premendo sul pulsante **Edit model card** nel repository del tuo modello.
+
+Dai un'occhiata alla [scheda del modello](https://huggingface.co/distilbert/distilbert-base-uncased) di DistilBert per avere un buon esempio del tipo di informazioni che una scheda di un modello deve includere. Per maggiori dettagli legati ad altre opzioni che puoi controllare nel file `README.md`, come l'impatto ambientale o widget di esempio, fai riferimento alla documentazione [qui](https://huggingface.co/docs/hub/models-cards).
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/multilingual.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/multilingual.md
new file mode 100644
index 0000000000000000000000000000000000000000..e9e85beec1d96642c72fd88b4c4c09929d95f7d0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/multilingual.md
@@ -0,0 +1,178 @@
+
+
+# Modelli multilingue per l'inferenza
+
+[[open-in-colab]]
+
+Ci sono diversi modelli multilingue in 🤗 Transformers, e il loro utilizzo per l'inferenza differisce da quello dei modelli monolingua. Non *tutti* gli utilizzi dei modelli multilingue sono però diversi. Alcuni modelli, come [google-bert/bert-base-multilingual-uncased](https://huggingface.co/google-bert/bert-base-multilingual-uncased), possono essere usati come un modello monolingua. Questa guida ti mostrerà come utilizzare modelli multilingue che utilizzano un modo diverso per fare l'inferenza.
+
+## XLM
+
+XLM ha dieci diversi checkpoint, di cui solo uno è monolingua. I nove checkpoint rimanenti possono essere suddivisi in due categorie: i checkpoint che utilizzano i language embeddings e quelli che non li utilizzano.
+
+### XLM con language embeddings
+
+I seguenti modelli XLM utilizzano gli embeddings linguistici per specificare la lingua utilizzata per l'inferenza:
+
+- `FacebookAI/xlm-mlm-ende-1024` (Modellazione mascherata del linguaggio (Masked language modeling, in inglese), Inglese-Tedesco)
+- `FacebookAI/xlm-mlm-enfr-1024` (Modellazione mascherata del linguaggio, Inglese-Francese)
+- `FacebookAI/xlm-mlm-enro-1024` (Modellazione mascherata del linguaggio, Inglese-Rumeno)
+- `FacebookAI/xlm-mlm-xnli15-1024` (Modellazione mascherata del linguaggio, lingue XNLI)
+- `FacebookAI/xlm-mlm-tlm-xnli15-1024` (Modellazione mascherata del linguaggio + traduzione, lingue XNLI)
+- `FacebookAI/xlm-clm-enfr-1024` (Modellazione causale del linguaggio, Inglese-Francese)
+- `FacebookAI/xlm-clm-ende-1024` (Modellazione causale del linguaggio, Inglese-Tedesco)
+
+Gli embeddings linguistici sono rappresentati come un tensore delle stesse dimensioni dell' `input_ids` passato al modello. I valori in questi tensori dipendono dal linguaggio usato e sono identificati dagli attributi `lang2id` e `id2lang` del tokenizer.
+
+In questo esempio, carica il checkpoint `FacebookAI/xlm-clm-enfr-1024` (Modellazione causale del linguaggio, Inglese-Francese):
+
+```py
+>>> import torch
+>>> from transformers import XLMTokenizer, XLMWithLMHeadModel
+
+>>> tokenizer = XLMTokenizer.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+>>> model = XLMWithLMHeadModel.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+```
+
+L'attributo `lang2id` del tokenizer mostra il linguaggio del modello e il suo ids:
+
+```py
+>>> print(tokenizer.lang2id)
+{'en': 0, 'fr': 1}
+```
+
+Poi, crea un esempio di input:
+
+```py
+>>> input_ids = torch.tensor([tokenizer.encode("Wikipedia was used to")]) # batch size of 1
+```
+
+Imposta l'id del linguaggio a `"en"` e usalo per definire il language embedding. Il language embedding è un tensore riempito con `0` perché questo è il language id per l'inglese. Questo tensore dovrebbe avere la stessa dimensione di `input_ids`.
+
+```py
+>>> language_id = tokenizer.lang2id["en"] # 0
+>>> langs = torch.tensor([language_id] * input_ids.shape[1]) # torch.tensor([0, 0, 0, ..., 0])
+
+>>> # We reshape it to be of size (batch_size, sequence_length)
+>>> langs = langs.view(1, -1) # is now of shape [1, sequence_length] (we have a batch size of 1)
+```
+
+Adesso puoi inserire `input_ids` e language embedding nel modello:
+
+```py
+>>> outputs = model(input_ids, langs=langs)
+```
+
+Lo script [run_generation.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-generation/run_generation.py) può generare testo tramite i language embeddings usando i checkpoints `xlm-clm`.
+
+### XLM senza language embeddings
+
+I seguenti modelli XLM non richiedono l'utilizzo dei language embeddings per fare inferenza:
+
+- `FacebookAI/xlm-mlm-17-1280` (Modellazione mascherata del linguaggio, 17 lingue)
+- `FacebookAI/xlm-mlm-100-1280` (Modellazione mascherata del linguaggio, 100 lingue)
+
+Questi modelli sono utilizzati per rappresentazioni generiche di frasi, a differenza dei precedenti checkpoints XML.
+
+## BERT
+
+Il seguente modello BERT può essere usato per compiti multilingue:
+
+- `google-bert/bert-base-multilingual-uncased` (Modellazione mascherata del linguaggio + Previsione della prossima frase, 102 lingue)
+- `google-bert/bert-base-multilingual-cased` (Modellazione mascherata del linguaggio + Previsione della prossima frase, 104 lingue)
+
+Questi modelli non richiedono language embeddings per fare inferenza. Riescono ad identificare il linguaggio dal contesto e inferire di conseguenza.
+
+## XLM-RoBERTa
+
+Il seguente modello XLM-RoBERTa può essere usato per compiti multilingue:
+
+- `FacebookAI/xlm-roberta-base` (Modellazione mascherata del linguaggio, 100 lingue)
+- `FacebookAI/xlm-roberta-large` (Modellazione mascherata del linguaggio, 100 lingue)
+
+XLM-RoBERTa è stato addestrato su 2.5TB di dati CommonCrawl appena creati e puliti in 100 lingue. Offre notevoli vantaggi rispetto ai modelli multilingue rilasciati in precedenza, come mBERT o XLM, in compiti come la classificazione, l'etichettatura delle sequenze e la risposta alle domande.
+
+## M2M100
+
+Il seguente modello M2M100 può essere usato per compiti multilingue:
+
+- `facebook/m2m100_418M` (Traduzione)
+- `facebook/m2m100_1.2B` (Traduzione)
+
+In questo esempio, carica il checkpoint `facebook/m2m100_418M` per tradurre dal cinese all'inglese. Puoi impostare la lingua di partenza nel tokenizer:
+
+```py
+>>> from transformers import M2M100ForConditionalGeneration, M2M100Tokenizer
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> chinese_text = "不要插手巫師的事務, 因為他們是微妙的, 很快就會發怒."
+
+>>> tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M", src_lang="zh")
+>>> model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M")
+```
+
+Applica il tokenizer al testo:
+
+```py
+>>> encoded_zh = tokenizer(chinese_text, return_tensors="pt")
+```
+
+M2M100 forza l'id della lingua obiettivo come primo token generato per tradurre nella lingua obiettivo. Imposta il parametro `forced_bos_token_id` a `en` nel metodo `generate` per tradurre in inglese:
+
+```py
+>>> generated_tokens = model.generate(**encoded_zh, forced_bos_token_id=tokenizer.get_lang_id("en"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+'Do not interfere with the matters of the witches, because they are delicate and will soon be angry.'
+```
+
+## MBart
+
+Il seguente modello MBart può essere usato per compiti multilingue:
+
+- `facebook/mbart-large-50-one-to-many-mmt` (Traduzione automatica multilingue uno-a-molti, 50 lingue)
+- `facebook/mbart-large-50-many-to-many-mmt` (Traduzione automatica multilingue molti-a-molti, 50 lingue)
+- `facebook/mbart-large-50-many-to-one-mmt` (Traduzione automatica multilingue molti-a-uno, 50 lingue)
+- `facebook/mbart-large-50` (Traduzione multilingue, 50 lingue)
+- `facebook/mbart-large-cc25`
+
+In questo esempio, carica il checkpoint `facebook/mbart-large-50-many-to-many-mmt` per tradurre dal finlandese all'inglese. Puoi impostare la lingua di partenza nel tokenizer:
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> fi_text = "Älä sekaannu velhojen asioihin, sillä ne ovat hienovaraisia ja nopeasti vihaisia."
+
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/mbart-large-50-many-to-many-mmt", src_lang="fi_FI")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
+```
+
+Applica il tokenizer sul testo:
+
+```py
+>>> encoded_en = tokenizer(en_text, return_tensors="pt")
+```
+
+MBart forza l'id della lingua obiettivo come primo token generato per tradurre nella lingua obiettivo. Imposta il parametro `forced_bos_token_id` a `en` nel metodo `generate` per tradurre in inglese:
+
+```py
+>>> generated_tokens = model.generate(**encoded_en, forced_bos_token_id=tokenizer.lang_code_to_id("en_XX"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+"Don't interfere with the wizard's affairs, because they are subtle, will soon get angry."
+```
+
+Se stai usando il checkpoint `facebook/mbart-large-50-many-to-one-mmt`, non hai bisogno di forzare l'id della lingua obiettivo come primo token generato altrimenti l'uso è lo stesso.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_hardware.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_hardware.md
new file mode 100644
index 0000000000000000000000000000000000000000..946dcb3238d057def0a73a86e7f483610effafa4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_hardware.md
@@ -0,0 +1,155 @@
+
+
+
+# Hardware ottimizzato per l'addestramento
+
+L'hardware utilizzato per eseguire l'addestramento del modello e l'inferenza può avere un grande effetto sulle prestazioni. Per un analisi approfondita delle GPUs, assicurati di dare un'occhiata all'eccellente [blog post](https://timdettmers.com/2020/09/07/which-gpu-for-deep-learning/) di Tim Dettmer.
+
+Diamo un'occhiata ad alcuni consigli pratici per la configurazione della GPU.
+
+## GPU
+Quando si addestrano modelli più grandi ci sono essenzialmente tre opzioni:
+- GPUs piu' grandi
+- Piu' GPUs
+- Piu' CPU e piu' NVMe (scaricato da [DeepSpeed-Infinity](main_classes/deepspeed#nvme-support))
+
+Iniziamo dal caso in cui ci sia una singola GPU.
+
+### Potenza e Raffreddamento
+
+Se hai acquistato una costosa GPU di fascia alta, assicurati di darle la potenza corretta e un raffreddamento sufficiente.
+
+**Potenza**:
+
+Alcune schede GPU consumer di fascia alta hanno 2 e talvolta 3 prese di alimentazione PCI-E a 8 pin. Assicurati di avere tanti cavi PCI-E a 8 pin indipendenti da 12 V collegati alla scheda quante sono le prese. Non utilizzare le 2 fessure a un'estremità dello stesso cavo (noto anche come cavo a spirale). Cioè se hai 2 prese sulla GPU, vuoi 2 cavi PCI-E a 8 pin che vanno dall'alimentatore alla scheda e non uno che abbia 2 connettori PCI-E a 8 pin alla fine! In caso contrario, non otterrai tutte le prestazioni ufficiali.
+
+Ciascun cavo di alimentazione PCI-E a 8 pin deve essere collegato a una guida da 12 V sul lato dell'alimentatore e può fornire fino a 150 W di potenza.
+
+Alcune altre schede possono utilizzare connettori PCI-E a 12 pin e questi possono fornire fino a 500-600 W di potenza.
+
+Le schede di fascia bassa possono utilizzare connettori a 6 pin, che forniscono fino a 75 W di potenza.
+
+Inoltre vuoi un alimentatore (PSU) di fascia alta che abbia una tensione stabile. Alcuni PSU di qualità inferiore potrebbero non fornire alla scheda la tensione stabile di cui ha bisogno per funzionare al massimo.
+
+E ovviamente l'alimentatore deve avere abbastanza Watt inutilizzati per alimentare la scheda.
+
+**Raffreddamento**:
+
+Quando una GPU si surriscalda, inizierà a rallentare e non fornirà le prestazioni mssimali e potrebbe persino spegnersi se diventasse troppo calda.
+
+È difficile dire l'esatta temperatura migliore a cui aspirare quando una GPU è molto caricata, ma probabilmente qualsiasi cosa al di sotto di +80°C va bene, ma più bassa è meglio - forse 70-75°C è un intervallo eccellente in cui trovarsi. È probabile che il rallentamento inizi a circa 84-90°C. Ma oltre alla limitazione delle prestazioni, una temperatura molto elevata prolungata è probabile che riduca la durata di una GPU.
+
+Diamo quindi un'occhiata a uno degli aspetti più importanti quando si hanno più GPU: la connettività.
+
+### Connettività multi-GPU
+
+Se utilizzi più GPU, il modo in cui le schede sono interconnesse può avere un enorme impatto sul tempo totale di allenamento. Se le GPU si trovano sullo stesso nodo fisico, puoi eseguire:
+
+```bash
+nvidia-smi topo -m
+```
+
+e ti dirà come sono interconnesse le GPU. Su una macchina con doppia GPU e collegata a NVLink, molto probabilmente vedrai qualcosa del tipo:
+
+```
+ GPU0 GPU1 CPU Affinity NUMA Affinity
+GPU0 X NV2 0-23 N/A
+GPU1 NV2 X 0-23 N/A
+```
+
+su una macchina diversa senza NVLink potremmo vedere:
+
+```
+ GPU0 GPU1 CPU Affinity NUMA Affinity
+GPU0 X PHB 0-11 N/A
+GPU1 PHB X 0-11 N/A
+```
+
+Il rapporto include questa legenda:
+
+```
+ X = Self
+ SYS = Connection traversing PCIe as well as the SMP interconnect between NUMA nodes (e.g., QPI/UPI)
+ NODE = Connection traversing PCIe as well as the interconnect between PCIe Host Bridges within a NUMA node
+ PHB = Connection traversing PCIe as well as a PCIe Host Bridge (typically the CPU)
+ PXB = Connection traversing multiple PCIe bridges (without traversing the PCIe Host Bridge)
+ PIX = Connection traversing at most a single PCIe bridge
+ NV# = Connection traversing a bonded set of # NVLinks
+```
+
+Quindi il primo rapporto `NV2` ci dice che le GPU sono interconnesse con 2 NVLinks e nel secondo report `PHB` abbiamo una tipica configurazione PCIe+Bridge a livello di consumatore.
+
+Controlla che tipo di connettività hai sulla tua configurazione. Alcuni di questi renderanno la comunicazione tra le carte più veloce (es. NVLink), altri più lenta (es. PHB).
+
+A seconda del tipo di soluzione di scalabilità utilizzata, la velocità di connettività potrebbe avere un impatto maggiore o minore. Se le GPU devono sincronizzarsi raramente, come in DDP, l'impatto di una connessione più lenta sarà meno significativo. Se le GPU devono scambiarsi messaggi spesso, come in ZeRO-DP, una connettività più veloce diventa estremamente importante per ottenere un addestramento più veloce.
+
+#### NVlink
+
+[NVLink](https://en.wikipedia.org/wiki/NVLink) è un collegamento di comunicazione a corto raggio multilinea seriale basato su cavo sviluppato da Nvidia.
+
+Ogni nuova generazione fornisce una larghezza di banda più veloce, ad es. ecco una citazione da [Nvidia Ampere GA102 GPU Architecture](https://www.nvidia.com/content/dam/en-zz/Solutions/geforce/ampere/pdf/NVIDIA-ampere-GA102-GPU-Architecture-Whitepaper-V1.pdf):
+
+> Third-Generation NVLink®
+> GA102 GPUs utilize NVIDIA’s third-generation NVLink interface, which includes four x4 links,
+> with each link providing 14.0625 GB/sec bandwidth in each direction between two GPUs. Four
+> links provide 56.25 GB/sec bandwidth in each direction, and 112.5 GB/sec total bandwidth
+> between two GPUs. Two RTX 3090 GPUs can be connected together for SLI using NVLink.
+> (Note that 3-Way and 4-Way SLI configurations are not supported.)
+
+Quindi più `X` si ottiene nel rapporto di `NVX` nell'output di `nvidia-smi topo -m`, meglio è. La generazione dipenderà dall'architettura della tua GPU.
+
+Confrontiamo l'esecuzione di un training del modello di linguaggio openai-community/gpt2 su un piccolo campione di wikitext
+
+I risultati sono:
+
+
+| NVlink | Time |
+| ----- | ---: |
+| Y | 101s |
+| N | 131s |
+
+
+Puoi vedere che NVLink completa l'addestramento circa il 23% più velocemente. Nel secondo benchmark utilizziamo `NCCL_P2P_DISABLE=1` per dire alle GPU di non utilizzare NVLink.
+
+Ecco il codice benchmark completo e gli output:
+
+```bash
+# DDP w/ NVLink
+
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 torchrun \
+--nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py --model_name_or_path openai-community/gpt2 \
+--dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 --do_train \
+--output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 101.9003, 'train_samples_per_second': 1.963, 'epoch': 0.69}
+
+# DDP w/o NVLink
+
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 NCCL_P2P_DISABLE=1 torchrun \
+--nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py --model_name_or_path openai-community/gpt2 \
+--dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 --do_train
+--output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 131.4367, 'train_samples_per_second': 1.522, 'epoch': 0.69}
+```
+
+Hardware: 2x TITAN RTX 24GB each + NVlink with 2 NVLinks (`NV2` in `nvidia-smi topo -m`)
+Software: `pytorch-1.8-to-be` + `cuda-11.0` / `transformers==4.3.0.dev0`
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_infer_cpu.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_infer_cpu.md
new file mode 100644
index 0000000000000000000000000000000000000000..baae51a5a97897fdb28e9a321862e9617f6cc8e1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_infer_cpu.md
@@ -0,0 +1,79 @@
+
+
+# Inferenza Efficiente su CPU
+
+Questa guida si concentra sull'inferenza di modelli di grandi dimensioni in modo efficiente sulla CPU.
+
+## `BetterTransformer` per inferenza più rapida
+
+Abbiamo integrato di recente `BetterTransformer` per fare inferenza più rapidamente con modelli per testi, immagini e audio. Visualizza la documentazione sull'integrazione [qui](https://huggingface.co/docs/optimum/bettertransformer/overview) per maggiori dettagli.
+
+## PyTorch JIT-mode (TorchScript)
+
+TorchScript è un modo di creare modelli serializzabili e ottimizzabili da codice PyTorch. Ogni programmma TorchScript può esere salvato da un processo Python e caricato in un processo dove non ci sono dipendenze Python.
+Comparandolo con l'eager mode di default, jit mode in PyTorch normalmente fornisce prestazioni migliori per l'inferenza del modello da parte di metodologie di ottimizzazione come la operator fusion.
+
+Per una prima introduzione a TorchScript, vedi la Introduction to [PyTorch TorchScript tutorial](https://pytorch.org/tutorials/beginner/Intro_to_TorchScript_tutorial.html#tracing-modules).
+
+### IPEX Graph Optimization con JIT-mode
+
+Intel® Extension per PyTorch fornnisce ulteriori ottimizzazioni in jit mode per i modelli della serie Transformers. Consigliamo vivamente agli utenti di usufruire dei vantaggi di Intel® Extension per PyTorch con jit mode. Alcuni operator patterns usati fequentemente dai modelli Transformers models sono già supportati in Intel® Extension per PyTorch con jit mode fusions. Questi fusion patterns come Multi-head-attention fusion, Concat Linear, Linear+Add, Linear+Gelu, Add+LayerNorm fusion and etc. sono abilitati e hanno buone performance. I benefici della fusion è fornito agli utenti in modo trasparente. In base alle analisi, il ~70% dei problemi più popolari in NLP question-answering, text-classification, and token-classification possono avere benefici sulle performance grazie ai fusion patterns sia per Float32 precision che per BFloat16 Mixed precision.
+
+Vedi maggiori informazioni per [IPEX Graph Optimization](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/features/graph_optimization.html).
+
+#### Installazione di IPEX
+
+I rilasci di IPEX seguono PyTorch, verifica i vari approcci per [IPEX installation](https://intel.github.io/intel-extension-for-pytorch/).
+
+### Utilizzo del JIT-mode
+
+Per abilitare JIT-mode in Trainer per evaluation e prediction, devi aggiungere `jit_mode_eval` negli argomenti di Trainer.
+
+
+
+per PyTorch >= 1.14.0. JIT-mode potrebe giovare a qualsiasi modello di prediction e evaluaion visto che il dict input è supportato in jit.trace
+
+per PyTorch < 1.14.0. JIT-mode potrebbe giovare ai modelli il cui ordine dei parametri corrisponde all'ordine delle tuple in ingresso in jit.trace, come i modelli per question-answering.
+Nel caso in cui l'ordine dei parametri seguenti non corrisponda all'ordine delle tuple in ingresso in jit.trace, come nei modelli di text-classification, jit.trace fallirà e lo cattureremo con una eccezione al fine di renderlo un fallback. Il logging è usato per notificare gli utenti.
+
+
+
+Trovi un esempo con caso d'uso in [Transformers question-answering](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)
+
+- Inference using jit mode on CPU:
+
+python run_qa.py \
+--model_name_or_path csarron/bert-base-uncased-squad-v1 \
+--dataset_name squad \
+--do_eval \
+--max_seq_length 384 \
+--doc_stride 128 \
+--output_dir /tmp/ \
+--no_cuda \
+--jit_mode_eval
+
+- Inference with IPEX using jit mode on CPU:
+
+python run_qa.py \
+--model_name_or_path csarron/bert-base-uncased-squad-v1 \
+--dataset_name squad \
+--do_eval \
+--max_seq_length 384 \
+--doc_stride 128 \
+--output_dir /tmp/ \
+--no_cuda \
+--use_ipex \
+--jit_mode_eval
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_infer_gpu_many.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_infer_gpu_many.md
new file mode 100644
index 0000000000000000000000000000000000000000..b78cb34e1d6d813f28a41f98a367f5574cab547b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_infer_gpu_many.md
@@ -0,0 +1,28 @@
+
+
+# Inferenza Efficiente su GPU Multiple
+
+Questo documento contiene informazioni su come fare inferenza in maniera efficiente su GPU multiple.
+
+
+
+Nota: Un setup con GPU multiple può utilizzare la maggior parte delle strategie descritte nella [sezione con GPU singola](./perf_infer_gpu_one). Tuttavia, è necessario conoscere delle tecniche semplici che possono essere utilizzate per un risultato migliore.
+
+
+
+## `BetterTransformer` per inferenza più rapida
+
+Abbiamo recentemente integrato `BetterTransformer` per inferenza più rapida su multi-GPU per modelli su testo, immagini e audio. Controlla il documento con queste integrazioni [qui](https://huggingface.co/docs/optimum/bettertransformer/overview) per maggiori dettagli.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_infer_gpu_one.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_infer_gpu_one.md
new file mode 100644
index 0000000000000000000000000000000000000000..e618ec34a1bd06a683b6db1a62c11fb563486ffe
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_infer_gpu_one.md
@@ -0,0 +1,112 @@
+
+
+# Inferenza efficiente su GPU singola
+
+Questo documento sarà presto completato con informazioni su come effetture l'inferenza su una singola GPU. Nel frattempo è possibile consultare [la guida per l'addestramento su una singola GPU](perf_train_gpu_one) e [la guida per l'inferenza su CPU](perf_infer_cpu).
+
+## `BetterTransformer` per l'inferenza più veloce
+
+Abbiamo recentemente integrato `BetterTransformer` per velocizzare l'inferenza su GPU per modelli di testo, immagini e audio. Per maggiori dettagli, consultare la documentazione su questa integrazione [qui](https://huggingface.co/docs/optimum/bettertransformer/overview).
+
+## Integrazione di `bitsandbytes` per Int8 mixed-precision matrix decomposition
+
+
+
+Nota che questa funzione può essere utilizzata anche nelle configurazioni multi GPU.
+
+
+
+Dal paper [`LLM.int8() : 8-bit Matrix Multiplication for Transformers at Scale`](https://arxiv.org/abs/2208.07339), noi supportiamo l'integrazione di Hugging Face per tutti i modelli dell'Hub con poche righe di codice.
+Il metodo `nn.Linear` riduce la dimensione di 2 per i pesi `float16` e `bfloat16` e di 4 per i pesi `float32`, con un impatto quasi nullo sulla qualità, operando sugli outlier in half-precision.
+
+
+
+Il metodo Int8 mixed-precision matrix decomposition funziona separando la moltiplicazione tra matrici in due flussi: (1) una matrice di flusso di outlier di caratteristiche sistematiche moltiplicata in fp16, (2) in flusso regolare di moltiplicazione di matrici int8 (99,9%). Con questo metodo, è possibile effettutare inferenza int8 per modelli molto grandi senza degrado predittivo.
+Per maggiori dettagli sul metodo, consultare il [paper](https://arxiv.org/abs/2208.07339) o il nostro [blogpost sull'integrazione](https://huggingface.co/blog/hf-bitsandbytes-integration).
+
+
+
+Nota che è necessaria una GPU per eseguire modelli di tipo mixed-8bit, poiché i kernel sono stati compilati solo per le GPU. Prima di utilizzare questa funzione, assicurarsi di disporre di memoria sufficiente sulla GPU per memorizzare un quarto del modello (o la metà se i pesi del modello sono in mezza precisione).
+Di seguito sono riportate alcune note per aiutarvi a utilizzare questo modulo, oppure seguite le dimostrazioni su [Google colab](#colab-demos).
+
+### Requisiti
+
+- Se si dispone di `bitsandbytes<0.37.0`, assicurarsi di eseguire su GPU NVIDIA che supportano tensor cores a 8 bit (Turing, Ampere o architetture più recenti - ad esempio T4, RTX20s RTX30s, A40-A100). Per `bitsandbytes>=0.37.0`, tutte le GPU dovrebbero essere supportate.
+- Installare la versione corretta di `bitsandbytes` eseguendo:
+`pip install bitsandbytes>=0.31.5`.
+- Installare `accelerate`
+`pip install accelerate>=0.12.0`
+
+### Esecuzione di modelli mixed-Int8 - configurazione per singola GPU
+
+Dopo aver installato le librerie necessarie, per caricare il tuo modello mixed 8-bit è il seguente:
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+model_name = "bigscience/bloom-2b5"
+model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+
+Per la generazione di testo, si consiglia di:
+
+* utilizzare il metodo `generate()` del modello invece della funzione `pipeline()`. Sebbene l'inferenza sia possibile con la funzione `pipeline()`, essa non è ottimizzata per i modelli mixed-8bit e sarà più lenta rispetto all'uso del metodo `generate()`. Inoltre, alcune strategie di campionamento, come il campionamento nucleaus, non sono supportate dalla funzione `pipeline()` per i modelli mixed-8bit.
+* collocare tutti gli ingressi sullo stesso dispositivo del modello.
+
+Ecco un semplice esempio:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model_name = "bigscience/bloom-2b5"
+tokenizer = AutoTokenizer.from_pretrained(model_name)
+model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+
+text = "Hello, my llama is cute"
+inputs = tokenizer(prompt, return_tensors="pt").to("cuda")
+generated_ids = model.generate(**inputs)
+outputs = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+```
+
+
+### Esecuzione di modelli mixed-8bit - configurazione multi GPU
+
+Usare il seguente modo caricare il modello mixed-8bit su più GPU (stesso comando della configurazione a GPU singola):
+```py
+model_name = "bigscience/bloom-2b5"
+model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+Puoi controllare la RAM della GPU che si vuole allocare su ogni GPU usando `accelerate`. Utilizzare l'argomento `max_memory` come segue:
+
+```py
+max_memory_mapping = {0: "1GB", 1: "2GB"}
+model_name = "bigscience/bloom-3b"
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ model_name, device_map="auto", load_in_8bit=True, max_memory=max_memory_mapping
+)
+```
+In questo esempio, la prima GPU utilizzerà 1 GB di memoria e la seconda 2 GB.
+
+### Colab demos
+
+Con questo metodo è possibile inferire modelli che prima non era possibile inferire su Google Colab.
+Guardate la demo per l'esecuzione di T5-11b (42GB in fp32)! Utilizzo la quantizzazione a 8 bit su Google Colab:
+
+[](https://colab.research.google.com/drive/1YORPWx4okIHXnjW7MSAidXN29mPVNT7F?usp=sharing)
+
+Oppure questa demo di BLOOM-3B:
+
+[](https://colab.research.google.com/drive/1qOjXfQIAULfKvZqwCen8-MoWKGdSatZ4?usp=sharing)
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_infer_special.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_infer_special.md
new file mode 100644
index 0000000000000000000000000000000000000000..3e2c0a5c288e379f4aa029bc2cbf6d3d72ea260f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_infer_special.md
@@ -0,0 +1,18 @@
+
+
+# Inferenza su Hardware Specializzato
+
+Questo documento sarà completato a breve con la documentazione per l'inferenza su hardware specializzato. Nel frattempo puoi controllare [la guida per fare inferenza sulle CPU](perf_infer_cpu).
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_train_cpu.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_train_cpu.md
new file mode 100644
index 0000000000000000000000000000000000000000..ff71d10d5c9d6c1fdbc0ddeecc4126a35558cf54
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_train_cpu.md
@@ -0,0 +1,69 @@
+
+
+# Addestramento efficiente su CPU
+
+Questa guida si concentra su come addestrare in maniera efficiente grandi modelli su CPU.
+
+## Mixed precision con IPEX
+
+IPEX è ottimizzato per CPU con AVX-512 o superiore, e funziona per le CPU con solo AVX2. Pertanto, si prevede che le prestazioni saranno più vantaggiose per le le CPU Intel con AVX-512 o superiori, mentre le CPU con solo AVX2 (ad esempio, le CPU AMD o le CPU Intel più vecchie) potrebbero ottenere prestazioni migliori con IPEX, ma non sono garantite. IPEX offre ottimizzazioni delle prestazioni per l'addestramento della CPU sia con Float32 che con BFloat16. L'uso di BFloat16 è l'argomento principale delle seguenti sezioni.
+
+Il tipo di dati a bassa precisione BFloat16 è stato supportato in modo nativo su 3rd Generation Xeon® Scalable Processors (aka Cooper Lake) con AVX512 e sarà supportata dalla prossima generazione di Intel® Xeon® Scalable Processors con Intel® Advanced Matrix Extensions (Intel® AMX) instruction set con prestazioni ulteriormente migliorate. L'Auto Mixed Precision per il backende della CPU è stato abilitato da PyTorch-1.10. allo stesso tempo, il supporto di Auto Mixed Precision con BFloat16 per CPU e l'ottimizzazione degli operatori BFloat16 è stata abilitata in modo massiccio in Intel® Extension per PyTorch, and parzialmente aggiornato al branch master di PyTorch. Gli utenti possono ottenere prestazioni migliori ed users experience con IPEX Auto Mixed Precision..
+
+Vedi informazioni più dettagliate su [Auto Mixed Precision](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/features/amp.html).
+
+### Installazione di IPEX:
+
+Il rilascio di IPEX segue quello di PyTorch, da installare via pip:
+
+| PyTorch Version | IPEX version |
+| :---------------: | :----------: |
+| 1.13 | 1.13.0+cpu |
+| 1.12 | 1.12.300+cpu |
+| 1.11 | 1.11.200+cpu |
+| 1.10 | 1.10.100+cpu |
+
+```bash
+pip install intel_extension_for_pytorch== -f https://developer.intel.com/ipex-whl-stable-cpu
+```
+
+Vedi altri approcci per [IPEX installation](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/installation.html).
+
+### Utilizzo nel Trainer
+
+Per abilitare la auto mixed precision con IPEX in Trainer, l'utende dovrebbe aggiungere `use_ipex`, `bf16` e `no_cuda` negli argomenti del comando di addestramento.
+
+Vedi un sempio di un caso d'uso [Transformers question-answering](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)
+
+- Training with IPEX using BF16 auto mixed precision on CPU:
+
+ python run_qa.py \
+--model_name_or_path google-bert/bert-base-uncased \
+--dataset_name squad \
+--do_train \
+--do_eval \
+--per_device_train_batch_size 12 \
+--learning_rate 3e-5 \
+--num_train_epochs 2 \
+--max_seq_length 384 \
+--doc_stride 128 \
+--output_dir /tmp/debug_squad/ \
+--use_ipex \
+--bf16 --no_cuda
+
+### Esempi pratici
+
+Blog: [Accelerating PyTorch Transformers with Intel Sapphire Rapids](https://huggingface.co/blog/intel-sapphire-rapids)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_train_cpu_many.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_train_cpu_many.md
new file mode 100644
index 0000000000000000000000000000000000000000..c1f8833829ac3bc0df0481f4a64c6102538d27dd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_train_cpu_many.md
@@ -0,0 +1,141 @@
+
+
+# Addestramento effciente su multiple CPU
+
+Quando l'addestramento su una singola CPU è troppo lento, possiamo usare CPU multiple. Quasta guida si concentra su DDP basato su PyTorch abilitando l'addetramento distribuito su CPU in maniera efficiente.
+
+## Intel® oneCCL Bindings per PyTorch
+
+[Intel® oneCCL](https://github.com/oneapi-src/oneCCL) (collective communications library) è una libreria per l'addestramento efficiente del deep learning in distribuito e implementa collettivi come allreduce, allgather, alltoall. Per maggiori informazioni su oneCCL, fai riferimento a [oneCCL documentation](https://spec.oneapi.com/versions/latest/elements/oneCCL/source/index.html) e [oneCCL specification](https://spec.oneapi.com/versions/latest/elements/oneCCL/source/index.html).
+
+Il modulo `oneccl_bindings_for_pytorch` (`torch_ccl` precedentemente alla versione 1.12) implementa PyTorch C10D ProcessGroup API e può essere caricato dinamicamente com external ProcessGroup e funziona solo su piattaforma Linux al momento.
+
+Qui trovi informazioni più dettagliate per [oneccl_bind_pt](https://github.com/intel/torch-ccl).
+
+### Intel® oneCCL Bindings per l'installazione PyTorch:
+
+I file wheel sono disponibili per le seguenti versioni di Python:
+
+| Extension Version | Python 3.6 | Python 3.7 | Python 3.8 | Python 3.9 | Python 3.10 |
+| :---------------: | :--------: | :--------: | :--------: | :--------: | :---------: |
+| 1.13.0 | | √ | √ | √ | √ |
+| 1.12.100 | | √ | √ | √ | √ |
+| 1.12.0 | | √ | √ | √ | √ |
+| 1.11.0 | | √ | √ | √ | √ |
+| 1.10.0 | √ | √ | √ | √ | |
+
+```bash
+pip install oneccl_bind_pt=={pytorch_version} -f https://developer.intel.com/ipex-whl-stable-cpu
+```
+
+dove `{pytorch_version}` deve essere la tua versione di PyTorch, per l'stanza 1.13.0.
+Verifica altri approcci per [oneccl_bind_pt installation](https://github.com/intel/torch-ccl).
+Le versioni di oneCCL e PyTorch devono combaciare.
+
+
+
+oneccl_bindings_for_pytorch 1.12.0 prebuilt wheel does not work with PyTorch 1.12.1 (it is for PyTorch 1.12.0)
+PyTorch 1.12.1 should work with oneccl_bindings_for_pytorch 1.12.100
+
+
+
+## Intel® MPI library
+
+Usa questa implementazione basata su standard MPI per fornire una architettura flessibile, efficiente, scalabile su cluster per Intel®. Questo componente è parte di Intel® oneAPI HPC Toolkit.
+
+oneccl_bindings_for_pytorch è installato insieme al set di strumenti MPI. Necessità di reperire l'ambiente prima di utilizzarlo.
+
+per Intel® oneCCL >= 1.12.0
+
+```bash
+oneccl_bindings_for_pytorch_path=$(python -c "from oneccl_bindings_for_pytorch import cwd; print(cwd)")
+source $oneccl_bindings_for_pytorch_path/env/setvars.sh
+```
+
+per Intel® oneCCL con versione < 1.12.0
+
+```bash
+torch_ccl_path=$(python -c "import torch; import torch_ccl; import os; print(os.path.abspath(os.path.dirname(torch_ccl.__file__)))")
+source $torch_ccl_path/env/setvars.sh
+```
+
+#### Installazione IPEX:
+
+IPEX fornisce ottimizzazioni delle prestazioni per l'addestramento della CPU sia con Float32 che con BFloat16; puoi fare riferimento a [single CPU section](./perf_train_cpu).
+
+Il seguente "Utilizzo in Trainer" prende come esempio mpirun nella libreria Intel® MPI.
+
+## Utilizzo in Trainer
+
+Per abilitare l'addestramento distribuito multi CPU nel Trainer con il ccl backend, gli utenti devono aggiungere **`--ddp_backend ccl`** negli argomenti del comando.
+
+Vediamo un esempio per il [question-answering example](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)
+
+Il seguente comando abilita due processi sul nodo Xeon, con un processo in esecuzione per ogni socket. Le variabili OMP_NUM_THREADS/CCL_WORKER_COUNT possono essere impostate per una prestazione ottimale.
+
+```shell script
+ export CCL_WORKER_COUNT=1
+ export MASTER_ADDR=127.0.0.1
+ mpirun -n 2 -genv OMP_NUM_THREADS=23 \
+ python3 run_qa.py \
+ --model_name_or_path google-bert/bert-large-uncased \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --per_device_train_batch_size 12 \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir /tmp/debug_squad/ \
+ --no_cuda \
+ --ddp_backend ccl \
+ --use_ipex
+```
+
+Il seguente comando abilita l'addestramento per un totale di quattro processi su due Xeon (node0 e node1, prendendo node0 come processo principale), ppn (processes per node) è impostato a 2, on un processo in esecuzione per ogni socket. Le variabili OMP_NUM_THREADS/CCL_WORKER_COUNT possono essere impostate per una prestazione ottimale.
+
+In node0, è necessario creare un file di configurazione che contenga gli indirizzi IP di ciascun nodo (per esempio hostfile) e passare il percorso del file di configurazione come parametro.
+
+```shell script
+ cat hostfile
+ xxx.xxx.xxx.xxx #node0 ip
+ xxx.xxx.xxx.xxx #node1 ip
+```
+
+A questo punto, esegui il seguente comando nel nodo0 e **4DDP** sarà abilitato in node0 e node1 con BF16 auto mixed precision:
+
+```shell script
+ export CCL_WORKER_COUNT=1
+ export MASTER_ADDR=xxx.xxx.xxx.xxx #node0 ip
+ mpirun -f hostfile -n 4 -ppn 2 \
+ -genv OMP_NUM_THREADS=23 \
+ python3 run_qa.py \
+ --model_name_or_path google-bert/bert-large-uncased \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --per_device_train_batch_size 12 \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir /tmp/debug_squad/ \
+ --no_cuda \
+ --ddp_backend ccl \
+ --use_ipex \
+ --bf16
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_train_special.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_train_special.md
new file mode 100644
index 0000000000000000000000000000000000000000..afe05d801d66e3cfd731964335aedd33a6cb79b8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_train_special.md
@@ -0,0 +1,24 @@
+
+
+# Addestramento su Hardware Specializzato
+
+
+
+ Nota: Molte delle strategie introdotte nella [sezione sulla GPU singola](perf_train_gpu_one) (come mixed precision training o gradient accumulation) e [sezione multi-GPU](perf_train_gpu_many) sono generiche e applicabili all'addestramento di modelli in generale quindi assicurati di dargli un'occhiata prima di immergerti in questa sezione.
+
+
+
+Questo documento sarà presto completato con informazioni su come effettuare la formazione su hardware specializzato.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_train_tpu.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_train_tpu.md
new file mode 100644
index 0000000000000000000000000000000000000000..663f83c499cba41e8910916b861380cc9072daae
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/perf_train_tpu.md
@@ -0,0 +1,24 @@
+
+
+# Addestramento su TPU
+
+
+
+ Nota: Molte delle strategie introdotte nella [sezione sulla GPU singola](perf_train_gpu_one) (come mixed precision training o gradient accumulation) e [sezione multi-GPU](perf_train_gpu_many) sono generiche e applicabili all'addestramento di modelli in generale quindi assicurati di dargli un'occhiata prima di immergerti in questa sezione.
+
+
+
+Questo documento sarà presto completato con informazioni su come effettuare la formazione su TPU.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/pipeline_tutorial.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/pipeline_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..87f3166623b05a31beecbae1893dc5bc6d12192a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/pipeline_tutorial.md
@@ -0,0 +1,152 @@
+
+
+# Pipeline per l'inferenza
+
+La [`pipeline`] rende semplice usare qualsiasi modello dal [Model Hub](https://huggingface.co/models) per fare inferenza su diversi compiti come generazione del testo, segmentazione di immagini e classificazione di audio. Anche se non hai esperienza con una modalità specifica o non comprendi bene il codice che alimenta i modelli, è comunque possibile utilizzarli con l'opzione [`pipeline`]! Questa esercitazione ti insegnerà a:
+
+* Usare una [`pipeline`] per fare inferenza.
+* Usare uno specifico tokenizer o modello.
+* Usare una [`pipeline`] per compiti che riguardano audio e video.
+
+
+
+Dai un'occhiata alla documentazione di [`pipeline`] per una lista completa dei compiti supportati.
+
+
+
+## Utilizzo della Pipeline
+
+Nonostante ogni compito abbia una [`pipeline`] associata, è più semplice utilizzare l'astrazione generica della [`pipeline`] che contiene tutte quelle specifiche per ogni mansione. La [`pipeline`] carica automaticamente un modello predefinito e un tokenizer in grado di fare inferenza per il tuo compito.
+
+1. Inizia creando una [`pipeline`] e specificando il compito su cui fare inferenza:
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline(task="text-generation")
+```
+
+2. Inserisci il testo in input nella [`pipeline`]:
+
+```py
+>>> generator(
+... "Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone"
+... ) # doctest: +SKIP
+[{'generated_text': 'Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone, Seven for the Iron-priests at the door to the east, and thirteen for the Lord Kings at the end of the mountain'}]
+```
+
+Se hai più di un input, inseriscilo in una lista:
+
+```py
+>>> generator(
+... [
+... "Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone",
+... "Nine for Mortal Men, doomed to die, One for the Dark Lord on his dark throne",
+... ]
+... ) # doctest: +SKIP
+```
+
+Qualsiasi parametro addizionale per il tuo compito può essere incluso nella [`pipeline`]. La mansione `text-generation` ha un metodo [`~generation.GenerationMixin.generate`] con diversi parametri per controllare l'output. Ad esempio, se desideri generare più di un output, utilizza il parametro `num_return_sequences`:
+
+```py
+>>> generator(
+... "Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone",
+... num_return_sequences=2,
+... ) # doctest: +SKIP
+```
+
+### Scegliere modello e tokenizer
+
+La [`pipeline`] accetta qualsiasi modello dal [Model Hub](https://huggingface.co/models). Ci sono tag nel Model Hub che consentono di filtrare i modelli per attività. Una volta che avrai scelto il modello appropriato, caricalo usando la corrispondente classe `AutoModelFor` e [`AutoTokenizer`]. Ad esempio, carica la classe [`AutoModelForCausalLM`] per un compito di causal language modeling:
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForCausalLM
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilgpt2")
+>>> model = AutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+Crea una [`pipeline`] per il tuo compito, specificando il modello e il tokenizer che hai caricato:
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline(task="text-generation", model=model, tokenizer=tokenizer)
+```
+
+Inserisci il testo di input nella [`pipeline`] per generare del testo:
+
+```py
+>>> generator(
+... "Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone"
+... ) # doctest: +SKIP
+[{'generated_text': 'Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone, Seven for the Dragon-lords (for them to rule in a world ruled by their rulers, and all who live within the realm'}]
+```
+
+## Audio pipeline
+
+La flessibilità della [`pipeline`] fa si che possa essere estesa ad attività sugli audio.
+
+Per esempio, classifichiamo le emozioni in questo clip audio:
+
+```py
+>>> from datasets import load_dataset
+>>> import torch
+
+>>> torch.manual_seed(42) # doctest: +IGNORE_RESULT
+>>> ds = load_dataset("hf-internal-testing/librispeech_asr_demo", "clean", split="validation")
+>>> audio_file = ds[0]["audio"]["path"]
+```
+
+Trova un modello per la [classificazione audio](https://huggingface.co/models?pipeline_tag=audio-classification) sul Model Hub per eseguire un compito di riconoscimento automatico delle emozioni e caricalo nella [`pipeline`]:
+
+```py
+>>> from transformers import pipeline
+
+>>> audio_classifier = pipeline(
+... task="audio-classification", model="ehcalabres/wav2vec2-lg-xlsr-en-speech-emotion-recognition"
+... )
+```
+
+Inserisci il file audio nella [`pipeline`]:
+
+```py
+>>> preds = audio_classifier(audio_file)
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.1315, 'label': 'calm'}, {'score': 0.1307, 'label': 'neutral'}, {'score': 0.1274, 'label': 'sad'}, {'score': 0.1261, 'label': 'fearful'}, {'score': 0.1242, 'label': 'happy'}]
+```
+
+## Vision pipeline
+
+Infine, usare la [`pipeline`] per le attività sulle immagini è praticamente la stessa cosa.
+
+Specifica la tua attività e inserisci l'immagine nel classificatore. L'immagine può essere sia un link che un percorso sul tuo pc in locale. Per esempio, quale specie di gatto è raffigurata qui sotto?
+
+
+
+```py
+>>> from transformers import pipeline
+
+>>> vision_classifier = pipeline(task="image-classification")
+>>> preds = vision_classifier(
+... images="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4335, 'label': 'lynx, catamount'}, {'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}, {'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}, {'score': 0.0239, 'label': 'Egyptian cat'}, {'score': 0.0229, 'label': 'tiger cat'}]
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/pr_checks.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/pr_checks.md
new file mode 100644
index 0000000000000000000000000000000000000000..caa5fe32965bde77bb52065d94f5f829a432091f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/pr_checks.md
@@ -0,0 +1,135 @@
+
+
+# Controlli su una Pull Request
+
+Quando apri una pull request sui 🤗 Transformers, vengono eseguiti un discreto numero di controlli per assicurarsi che la patch che stai aggiungendo non stia rompendo qualcosa di esistente. Questi controlli sono di quattro tipi:
+- test regolari
+- costruzione della documentazione
+- stile del codice e della documentazione
+- coerenza generale del repository
+
+In questo documento, cercheremo di spiegare quali sono i vari controlli e le loro ragioni, oltre a spiegare come eseguire il debug locale se uno di essi fallisce sulla tua PR.
+
+Nota che tutti richiedono un'installazione dev:
+
+```bash
+pip install transformers[dev]
+```
+
+o un'installazione modificabile:
+
+```bash
+pip install -e .[dev]
+```
+
+all'interno del repo Transformers.
+
+## Tests
+
+Tutti i job che iniziano con `ci/circleci: run_tests_` eseguono parti della suite di test dei Transformers. Ognuno di questi job si concentra su una parte della libreria in un determinato ambiente: per esempio `ci/circleci: run_tests_pipelines_tf` esegue il test delle pipeline in un ambiente in cui è installato solo TensorFlow.
+
+Nota che per evitare di eseguire i test quando non ci sono cambiamenti reali nei moduli che si stanno testando, ogni volta viene eseguita solo una parte della suite di test: viene eseguita una utility per determinare le differenze nella libreria tra prima e dopo la PR (ciò che GitHub mostra nella scheda "Files changes") e sceglie i test che sono stati impattati dalla diff. Questa utility può essere eseguita localmente con:
+
+```bash
+python utils/tests_fetcher.py
+```
+
+dalla root del repo Transformers. Di seguito ciò che farà:
+
+1. Controlla per ogni file nel diff se le modifiche sono nel codice o solo nei commenti o nelle docstrings. Vengono mantenuti solo i file con modifiche reali al codice.
+2. Costruisce una mappa interna che fornisce per ogni file del codice sorgente della libreria tutti i file su cui ha un impatto ricorsivo. Si dice che il modulo A ha un impatto sul modulo B se il modulo B importa il modulo A. Per l'impatto ricorsivo, abbiamo bisogno di una catena di moduli che va dal modulo A al modulo B in cui ogni modulo importa il precedente.
+3. Applica questa mappa ai file raccolti nel passaggio 1, si ottiene l'elenco dei file del modello interessati dalla PR.
+4. Mappa ciascuno di questi file con i corrispondenti file di test e ottiene l'elenco dei test da eseguire.
+
+Quando esegui lo script in locale, dovresti ottenere la stampa dei risultati dei passi 1, 3 e 4 e quindi sapere quali test sono stati eseguiti. Lo script creerà anche un file chiamato `test_list.txt` che contiene l'elenco dei test da eseguire e che puoi eseguire localmente con il seguente comando:
+
+```bash
+python -m pytest -n 8 --dist=loadfile -rA -s $(cat test_list.txt)
+```
+
+Nel caso in cui qualcosa sia sfuggito, l'intera suite di test viene eseguita quotidianamente.
+
+## Build della documentazione
+
+Il job `ci/circleci: build_doc` esegue una build della documentazione per assicurarsi che tutto sia a posto una volta che la PR è stata unita. Se questo passaggio fallisce, puoi controllare localmente entrando nella cartella `docs` del repo Transformers e digitare
+
+```bash
+make html
+```
+
+Sphinx non è noto per i suoi messaggi di errore chiari, quindi potrebbe essere necessario che provi alcune cose per trovare davvero la fonte dell'errore.
+
+## Stile del codice e della documentazione
+
+La formattazione del codice viene applicata a tutti i file sorgenti, agli esempi e ai test usando `black` e `isort`. Abbiamo anche uno strumento personalizzato che si occupa della formattazione delle docstring e dei file `rst` (`utils/style_doc.py`), così come dell'ordine dei lazy imports eseguiti nei file `__init__.py` dei Transformers (`utils/custom_init_isort.py`). Tutto questo può essere lanciato eseguendo
+
+```bash
+make style
+```
+
+I controlli della CI sono applicati all'interno del controllo `ci/circleci: check_code_quality`. Esegue anche `flake8`, che dà un'occhiata di base al codice e si lamenta se trova una variabile non definita o non utilizzata. Per eseguire questo controllo localmente, usare
+
+```bash
+make quality
+```
+
+Questa operazione può richiedere molto tempo, quindi per eseguire la stessa operazione solo sui file modificati nel branch corrente, eseguire
+
+```bash
+make fixup
+```
+
+Quest'ultimo comando eseguirà anche tutti i controlli aggiuntivi per la consistenza del repository. Diamogli un'occhiata.
+
+## Coerenza del repository
+
+All'interno sono raggruppati tutti i test per assicurarsi che la tua PR lasci il repository in un buono stato ed è eseguito dal controllo `ci/circleci: check_repository_consistency`. Puoi eseguire localmente questo controllo eseguendo quanto segue:
+
+```bash
+make repo-consistency
+```
+
+Questo verifica che:
+
+- Tutti gli oggetti aggiunti all'init sono documentati (eseguito da `utils/check_repo.py`)
+- Tutti i file `__init__.py` hanno lo stesso contenuto nelle loro due sezioni (eseguito da `utils/check_inits.py`)
+- Tutto il codice identificato come copia da un altro modulo è coerente con l'originale (eseguito da `utils/check_copies.py`)
+- Le traduzioni dei README e l'indice della documentazione hanno lo stesso elenco di modelli del README principale (eseguito da `utils/check_copies.py`)
+- Le tabelle autogenerate nella documentazione sono aggiornate (eseguito da `utils/check_table.py`)
+- La libreria ha tutti gli oggetti disponibili anche se non tutte le dipendenze opzionali sono installate (eseguito da `utils/check_dummies.py`)
+
+Se questo controllo fallisce, le prime due voci richiedono una correzione manuale, mentre le ultime quattro possono essere corrette automaticamente per te eseguendo il comando
+
+```bash
+make fix-copies
+```
+
+Ulteriori controlli riguardano le PR che aggiungono nuovi modelli, principalmente che:
+
+- Tutti i modelli aggiunti sono in un Auto-mapping (eseguita da `utils/check_repo.py`)
+
+- Tutti i modelli sono testati correttamente (eseguito da `utils/check_repo.py`)
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/preprocessing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/preprocessing.md
new file mode 100644
index 0000000000000000000000000000000000000000..6d7bc5b2e3df7e05a92f7b806fd470c457be1c03
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/preprocessing.md
@@ -0,0 +1,491 @@
+
+
+# Preprocess
+
+[[open-in-colab]]
+
+Prima di poter usare i dati in un modello, bisogna processarli in un formato accettabile per quest'ultimo. Un modello non comprende il testo grezzo, le immagini o l'audio. Bisogna convertire questi input in numeri e assemblarli all'interno di tensori. In questa esercitazione, tu potrai:
+
+* Preprocessare dati testuali con un tokenizer.
+* Preprocessare immagini o dati audio con un estrattore di caratteristiche.
+* Preprocessare dati per attività multimodali mediante un processore.
+
+## NLP
+
+
+
+Se stai pensando si utilizzare un modello preaddestrato, è importante utilizzare il tokenizer preaddestrato associato. Questo assicura che il testo sia separato allo stesso modo che nel corpus usato per l'addestramento, e venga usata la stessa mappatura tokens-to-index (solitamente indicato come il *vocabolario*) come nel preaddestramento.
+
+
+
+Iniziamo subito caricando un tokenizer preaddestrato con la classe [`AutoTokenizer`]. Questo scarica il *vocabolario* usato quando il modello è stato preaddestrato.
+
+### Tokenize
+
+Carica un tokenizer preaddestrato con [`AutoTokenizer.from_pretrained`]:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
+```
+
+Poi inserisci le tue frasi nel tokenizer:
+
+```py
+>>> encoded_input = tokenizer("Do not meddle in the affairs of wizards, for they are subtle and quick to anger.")
+>>> print(encoded_input)
+{'input_ids': [101, 2079, 2025, 19960, 10362, 1999, 1996, 3821, 1997, 16657, 1010, 2005, 2027, 2024, 11259, 1998, 4248, 2000, 4963, 1012, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+Il tokenizer restituisce un dizionario contenente tre oggetti importanti:
+
+* [input_ids](glossary#input-ids) sono gli indici che corrispondono ad ogni token nella frase.
+* [attention_mask](glossary#attention-mask) indicata se un token deve essere elaborato o no.
+* [token_type_ids](glossary#token-type-ids) identifica a quale sequenza appartiene un token se è presente più di una sequenza.
+
+Si possono decodificare gli `input_ids` per farsi restituire l'input originale:
+
+```py
+>>> tokenizer.decode(encoded_input["input_ids"])
+'[CLS] Do not meddle in the affairs of wizards, for they are subtle and quick to anger. [SEP]'
+```
+
+Come si può vedere, il tokenizer aggiunge due token speciali - `CLS` e `SEP` (classificatore e separatore) - alla frase. Non tutti i modelli hanno bisogno dei token speciali, ma se servono, il tokenizer li aggiungerà automaticamente.
+
+Se ci sono più frasi che vuoi processare, passale come una lista al tokenizer:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_inputs = tokenizer(batch_sentences)
+>>> print(encoded_inputs)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1]]}
+```
+
+### Pad
+
+Questo è un argomento importante. Quando processi un insieme di frasi potrebbero non avere tutte la stessa lunghezza. Questo è un problema perchè i tensori, in input del modello, devono avere dimensioni uniformi. Il padding è una strategia per assicurarsi che i tensori siano rettangolari aggiungendo uno speciale *padding token* alle frasi più corte.
+
+Imposta il parametro `padding` a `True` per imbottire le frasi più corte nel gruppo in modo che combacino con la massima lunghezza presente:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True)
+>>> print(encoded_input)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
+```
+
+Nota che il tokenizer aggiunge alle sequenze degli `0` perchè sono troppo corte!
+
+### Truncation
+
+L'altra faccia della medaglia è che avolte le sequenze possono essere troppo lunghe per essere gestite dal modello. In questo caso, avrai bisogno di troncare la sequenza per avere una lunghezza minore.
+
+Imposta il parametro `truncation` a `True` per troncare una sequenza alla massima lunghezza accettata dal modello:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True)
+>>> print(encoded_input)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
+```
+
+### Costruire i tensori
+
+Infine, vuoi che il tokenizer restituisca i tensori prodotti dal modello.
+
+Imposta il parametro `return_tensors` su `pt` per PyTorch, o `tf` per TensorFlow:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch, padding=True, truncation=True, return_tensors="pt")
+>>> print(encoded_input)
+{'input_ids': tensor([[ 101, 153, 7719, 21490, 1122, 1114, 9582, 1623, 102],
+ [ 101, 5226, 1122, 9649, 1199, 2610, 1236, 102, 0]]),
+ 'token_type_ids': tensor([[0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0]]),
+ 'attention_mask': tensor([[1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 1, 0]])}
+===PT-TF-SPLIT===
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch, padding=True, truncation=True, return_tensors="tf")
+>>> print(encoded_input)
+{'input_ids': ,
+ 'token_type_ids': ,
+ 'attention_mask': }
+```
+
+## Audio
+
+Gli input audio sono processati in modo differente rispetto al testo, ma l'obiettivo rimane lo stesso: creare sequenze numeriche che il modello può capire. Un [estrattore di caratteristiche](main_classes/feature_extractor) è progettato con lo scopo preciso di estrarre caratteristiche da immagini o dati audio grezzi e convertirli in tensori. Prima di iniziare, installa 🤗 Datasets per caricare un dataset audio e sperimentare:
+
+```bash
+pip install datasets
+```
+
+Carica il dataset [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) (vedi il 🤗 [Datasets tutorial](https://huggingface.co/docs/datasets/load_hub) per avere maggiori dettagli su come caricare un dataset):
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train")
+```
+
+Accedi al primo elemento della colonna `audio` per dare uno sguardo all'input. Richiamando la colonna `audio` sarà caricato automaticamente e ricampionato il file audio:
+
+```py
+>>> dataset[0]["audio"]
+{'array': array([ 0. , 0.00024414, -0.00024414, ..., -0.00024414,
+ 0. , 0. ], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~JOINT_ACCOUNT/602ba55abb1e6d0fbce92065.wav',
+ 'sampling_rate': 8000}
+```
+
+Questo restituisce tre oggetti:
+
+* `array` è il segnale vocale caricato - e potenzialmente ricampionato - come vettore 1D.
+* `path` il percorso del file audio.
+* `sampling_rate` si riferisce al numero di campioni del segnale vocale misurati al secondo.
+
+### Ricampionamento
+
+Per questo tutorial, puoi usare il modello [Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base). Come puoi vedere dalla model card, il modello Wav2Vec2 è preaddestrato su un campionamento vocale a 16kHz.È importante che la frequenza di campionamento dei tuoi dati audio combaci con la frequenza di campionamento del dataset usato per preaddestrare il modello. Se la frequenza di campionamento dei tuoi dati non è uguale dovrai ricampionare i tuoi dati audio.
+
+Per esempio, il dataset [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) ha una frequenza di campionamento di 8000kHz. Utilizzando il modello Wav2Vec2 su questo dataset, alzala a 16kHz:
+
+```py
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train")
+>>> dataset[0]["audio"]
+{'array': array([ 0. , 0.00024414, -0.00024414, ..., -0.00024414,
+ 0. , 0. ], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~JOINT_ACCOUNT/602ba55abb1e6d0fbce92065.wav',
+ 'sampling_rate': 8000}
+```
+
+1. Usa il metodo di 🤗 Datasets' [`cast_column`](https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.cast_column) per alzare la frequenza di campionamento a 16kHz:
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16_000))
+```
+
+2. Carica il file audio:
+
+```py
+>>> dataset[0]["audio"]
+{'array': array([ 2.3443763e-05, 2.1729663e-04, 2.2145823e-04, ...,
+ 3.8356509e-05, -7.3497440e-06, -2.1754686e-05], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~JOINT_ACCOUNT/602ba55abb1e6d0fbce92065.wav',
+ 'sampling_rate': 16000}
+```
+
+Come puoi notare, la `sampling_rate` adesso è 16kHz!
+
+### Feature extractor
+
+Il prossimo passo è caricare un estrattore di caratteristiche per normalizzare e fare padding sull'input. Quando applichiamo il padding sui dati testuali, uno `0` è aggiunto alle sequenze più brevi. La stessa idea si applica ai dati audio, l'estrattore di caratteristiche per gli audio aggiungerà uno `0` - interpretato come silenzio - agli `array`.
+
+Carica l'estrattore delle caratteristiche con [`AutoFeatureExtractor.from_pretrained`]:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base")
+```
+
+Inserisci l' `array` audio nell'estrattore delle caratteristiche. Noi raccomandiamo sempre di aggiungere il parametro `sampling_rate` nell'estrattore delle caratteristiche per correggere meglio qualche errore, dovuto ai silenzi, che potrebbe verificarsi.
+
+```py
+>>> audio_input = [dataset[0]["audio"]["array"]]
+>>> feature_extractor(audio_input, sampling_rate=16000)
+{'input_values': [array([ 3.8106556e-04, 2.7506407e-03, 2.8015103e-03, ...,
+ 5.6335266e-04, 4.6588284e-06, -1.7142107e-04], dtype=float32)]}
+```
+
+### Pad e truncate
+
+Come per il tokenizer, puoi applicare le operazioni padding o truncation per manipolare sequenze di variabili a lotti. Dai uno sguaro alla lunghezza delle sequenze di questi due campioni audio:
+
+```py
+>>> dataset[0]["audio"]["array"].shape
+(173398,)
+
+>>> dataset[1]["audio"]["array"].shape
+(106496,)
+```
+
+Come puoi vedere, il primo campione ha una sequenza più lunga del secondo. Crea una funzione che preprocesserà il dataset. Specifica una lunghezza massima del campione, e l'estrattore di features si occuperà di riempire o troncare la sequenza per coincidervi:
+
+```py
+>>> def preprocess_function(examples):
+... audio_arrays = [x["array"] for x in examples["audio"]]
+... inputs = feature_extractor(
+... audio_arrays,
+... sampling_rate=16000,
+... padding=True,
+... max_length=100000,
+... truncation=True,
+... )
+... return inputs
+```
+
+Applica la funzione ai primi esempi nel dataset:
+
+```py
+>>> processed_dataset = preprocess_function(dataset[:5])
+```
+
+Adesso guarda la lunghezza dei campioni elaborati:
+
+```py
+>>> processed_dataset["input_values"][0].shape
+(100000,)
+
+>>> processed_dataset["input_values"][1].shape
+(100000,)
+```
+
+La lunghezza dei campioni adesso coincide con la massima lunghezza impostata nelle funzione.
+
+## Vision
+
+Un estrattore di caratteristiche si può usare anche per processare immagini e per compiti di visione. Ancora una volta, l'obiettivo è convertire l'immagine grezza in un lotto di tensori come input.
+
+Carica il dataset [food101](https://huggingface.co/datasets/food101) per questa esercitazione. Usa il parametro `split` di 🤗 Datasets per caricare solo un piccolo campione dal dataset di addestramento poichè il set di dati è molto grande:
+
+```py
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("food101", split="train[:100]")
+```
+
+Secondo passo, dai uno sguardo alle immagini usando la caratteristica [`Image`](https://huggingface.co/docs/datasets/package_reference/main_classes.html?highlight=image#datasets.Image) di 🤗 Datasets:
+
+```py
+>>> dataset[0]["image"]
+```
+
+
+
+### Feature extractor
+
+Carica l'estrattore di caratteristiche [`AutoFeatureExtractor.from_pretrained`]:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("google/vit-base-patch16-224")
+```
+
+### Data augmentation
+
+Per le attività di visione, è usuale aggiungere alcuni tipi di data augmentation alle immagini come parte del preprocessing. Puoi aggiungere augmentations con qualsiasi libreria che preferisci, ma in questa esercitazione, userai il modulo [`transforms`](https://pytorch.org/vision/stable/transforms.html) di torchvision.
+
+1. Normalizza l'immagine e usa [`Compose`](https://pytorch.org/vision/master/generated/torchvision.transforms.Compose.html) per concatenare alcune trasformazioni - [`RandomResizedCrop`](https://pytorch.org/vision/main/generated/torchvision.transforms.RandomResizedCrop.html) e [`ColorJitter`](https://pytorch.org/vision/main/generated/torchvision.transforms.ColorJitter.html) - insieme:
+
+```py
+>>> from torchvision.transforms import Compose, Normalize, RandomResizedCrop, ColorJitter, ToTensor
+
+>>> normalize = Normalize(mean=feature_extractor.image_mean, std=feature_extractor.image_std)
+>>> _transforms = Compose(
+... [RandomResizedCrop(feature_extractor.size), ColorJitter(brightness=0.5, hue=0.5), ToTensor(), normalize]
+... )
+```
+
+2. Il modello accetta [`pixel_values`](model_doc/visionencoderdecoder#transformers.VisionEncoderDecoderModel.forward.pixel_values) come input. Questo valore è generato dall'estrattore di caratteristiche. Crea una funzione che genera `pixel_values` dai transforms:
+
+```py
+>>> def transforms(examples):
+... examples["pixel_values"] = [_transforms(image.convert("RGB")) for image in examples["image"]]
+... return examples
+```
+
+3. Poi utilizza 🤗 Datasets [`set_transform`](https://huggingface.co/docs/datasets/process#format-transform)per applicare al volo la trasformazione:
+
+```py
+>>> dataset.set_transform(transforms)
+```
+
+4. Adesso quando accedi all'immagine, puoi notare che l'estrattore di caratteristiche ha aggiunto `pixel_values` allo schema di input:
+
+```py
+>>> dataset[0]["image"]
+{'image': ,
+ 'label': 6,
+ 'pixel_values': tensor([[[ 0.0353, 0.0745, 0.1216, ..., -0.9922, -0.9922, -0.9922],
+ [-0.0196, 0.0667, 0.1294, ..., -0.9765, -0.9843, -0.9922],
+ [ 0.0196, 0.0824, 0.1137, ..., -0.9765, -0.9686, -0.8667],
+ ...,
+ [ 0.0275, 0.0745, 0.0510, ..., -0.1137, -0.1216, -0.0824],
+ [ 0.0667, 0.0824, 0.0667, ..., -0.0588, -0.0745, -0.0980],
+ [ 0.0353, 0.0353, 0.0431, ..., -0.0039, -0.0039, -0.0588]],
+
+ [[ 0.2078, 0.2471, 0.2863, ..., -0.9451, -0.9373, -0.9451],
+ [ 0.1608, 0.2471, 0.3098, ..., -0.9373, -0.9451, -0.9373],
+ [ 0.2078, 0.2706, 0.3020, ..., -0.9608, -0.9373, -0.8275],
+ ...,
+ [-0.0353, 0.0118, -0.0039, ..., -0.2392, -0.2471, -0.2078],
+ [ 0.0196, 0.0353, 0.0196, ..., -0.1843, -0.2000, -0.2235],
+ [-0.0118, -0.0039, -0.0039, ..., -0.0980, -0.0980, -0.1529]],
+
+ [[ 0.3961, 0.4431, 0.4980, ..., -0.9216, -0.9137, -0.9216],
+ [ 0.3569, 0.4510, 0.5216, ..., -0.9059, -0.9137, -0.9137],
+ [ 0.4118, 0.4745, 0.5216, ..., -0.9137, -0.8902, -0.7804],
+ ...,
+ [-0.2314, -0.1922, -0.2078, ..., -0.4196, -0.4275, -0.3882],
+ [-0.1843, -0.1686, -0.2000, ..., -0.3647, -0.3804, -0.4039],
+ [-0.1922, -0.1922, -0.1922, ..., -0.2941, -0.2863, -0.3412]]])}
+```
+
+Di seguito come si vede l'immagine dopo la fase di preprocessing. Come ci si aspetterebbe dalle trasformazioni applicate, l'immagine è stata ritagliata in modo casuale e le proprietà del colore sono diverse.
+
+```py
+>>> import numpy as np
+>>> import matplotlib.pyplot as plt
+
+>>> img = dataset[0]["pixel_values"]
+>>> plt.imshow(img.permute(1, 2, 0))
+```
+
+
+
+## Multimodal
+
+Per attività multimodali userai una combinazione di tutto quello che hai imparato poco fa e applicherai le tue competenze alla comprensione automatica del parlato (Automatic Speech Recognition - ASR). Questo significa che avrai bisogno di:
+
+* Un estrattore delle caratteristiche per processare i dati audio.
+* Il Tokenizer per processare i testi.
+
+Ritorna sul datasere [LJ Speech](https://huggingface.co/datasets/lj_speech):
+
+```py
+>>> from datasets import load_dataset
+
+>>> lj_speech = load_dataset("lj_speech", split="train")
+```
+
+Visto che sei interessato solo alle colonne `audio` e `text`, elimina tutte le altre:
+
+```py
+>>> lj_speech = lj_speech.map(remove_columns=["file", "id", "normalized_text"])
+```
+
+Adesso guarda le colonne `audio` e `text`:
+
+```py
+>>> lj_speech[0]["audio"]
+{'array': array([-7.3242188e-04, -7.6293945e-04, -6.4086914e-04, ...,
+ 7.3242188e-04, 2.1362305e-04, 6.1035156e-05], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/917ece08c95cf0c4115e45294e3cd0dee724a1165b7fc11798369308a465bd26/LJSpeech-1.1/wavs/LJ001-0001.wav',
+ 'sampling_rate': 22050}
+
+>>> lj_speech[0]["text"]
+'Printing, in the only sense with which we are at present concerned, differs from most if not from all the arts and crafts represented in the Exhibition'
+```
+
+Ricorda dalla sezione precedente sull'elaborazione dei dati audio, tu dovresti sempre [ricampionare](preprocessing#audio) la frequenza di campionamento dei tuoi dati audio per farla coincidere con quella del dataset usato dal modello preaddestrato:
+
+```py
+>>> lj_speech = lj_speech.cast_column("audio", Audio(sampling_rate=16_000))
+```
+
+### Processor
+
+Un processor combina un estrattore di caratteristiche e un tokenizer. Carica un processor con [`AutoProcessor.from_pretrained`]:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base-960h")
+```
+
+1. Crea una funzione che processi i dati audio in `input_values`, e tokenizza il testo in `labels`. Questi sono i tuoi input per il modello:
+
+```py
+>>> def prepare_dataset(example):
+... audio = example["audio"]
+
+... example.update(processor(audio=audio["array"], text=example["text"], sampling_rate=16000))
+
+... return example
+```
+
+2. Applica la funzione `prepare_dataset` ad un campione:
+
+```py
+>>> prepare_dataset(lj_speech[0])
+```
+
+Nota che il processor ha aggiunto `input_values` e `labels`. La frequenza di campionamento è stata corretta riducendola a 16kHz.
+
+Fantastico, ora dovresti essere in grado di preelaborare i dati per qualsiasi modalità e persino di combinare modalità diverse! Nella prossima esercitazione, impareremo a mettere a punto un modello sui dati appena pre-elaborati.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/quicktour.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/quicktour.md
new file mode 100644
index 0000000000000000000000000000000000000000..f0291a6167715a860af1dad07d41ada4d667a405
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/quicktour.md
@@ -0,0 +1,401 @@
+
+
+# Quick tour
+
+[[open-in-colab]]
+
+Entra in azione con 🤗 Transformers! Inizia utilizzando [`pipeline`] per un'inferenza veloce, carica un modello pre-allenato e un tokenizer con una [AutoClass](./model_doc/auto) per risolvere i tuoi compiti legati a testo, immagini o audio.
+
+
+
+Tutti gli esempi di codice presenti in questa documentazione hanno un pulsante in alto a sinistra che permette di selezionare tra PyTorch e TensorFlow. Se
+questo non è presente, ci si aspetta che il codice funzioni per entrambi i backend senza alcun cambiamento.
+
+
+
+## Pipeline
+
+[`pipeline`] è il modo più semplice per utilizzare un modello pre-allenato per un dato compito.
+
+
+
+Per maggiori dettagli legati alla [`pipeline`] e ai compiti ad essa associati, fai riferimento alla documentazione [qui](./main_classes/pipelines).
+
+
+
+### Utilizzo della Pipeline
+
+Nel seguente esempio, utilizzerai la [`pipeline`] per l'analisi del sentimento.
+
+Installa le seguenti dipendenze se non lo hai già fatto:
+
+
+
+
+```bash
+pip install torch
+```
+
+
+
+```bash
+pip install tensorflow
+```
+
+
+
+Importa [`pipeline`] e specifica il compito che vuoi completare:
+
+```py
+>>> from transformers import pipeline
+
+>>> classificatore = pipeline("sentiment-analysis", model="MilaNLProc/feel-it-italian-sentiment")
+```
+
+La pipeline scarica e salva il [modello pre-allenato](https://huggingface.co/MilaNLProc/feel-it-italian-sentiment) e il tokenizer per l'analisi del sentimento. Se non avessimo scelto un modello, la pipeline ne avrebbe scelto uno di default. Ora puoi utilizzare il `classifier` sul tuo testo obiettivo:
+
+```py
+>>> classificatore("Siamo molto felici di mostrarti la libreria 🤗 Transformers.")
+[{'label': 'positive', 'score': 0.9997}]
+```
+
+Per più di una frase, passa una lista di frasi alla [`pipeline`] la quale restituirà una lista di dizionari:
+
+```py
+>>> risultati = classificatore(
+... ["Siamo molto felici di mostrarti la libreria 🤗 Transformers.", "Speriamo te non la odierai."]
+... )
+>>> for risultato in risultati:
+... print(f"etichetta: {risultato['label']}, con punteggio: {round(risultato['score'], 4)}")
+etichetta: positive, con punteggio: 0.9998
+etichetta: negative, con punteggio: 0.9998
+```
+
+La [`pipeline`] può anche iterare su un dataset intero. Inizia installando la libreria [🤗 Datasets](https://huggingface.co/docs/datasets/):
+
+```bash
+pip install datasets
+```
+
+Crea una [`pipeline`] con il compito che vuoi risolvere e con il modello che vuoi utilizzare.
+
+```py
+>>> import torch
+>>> from transformers import pipeline
+
+>>> riconoscitore_vocale = pipeline(
+... "automatic-speech-recognition", model="radiogroup-crits/wav2vec2-xls-r-1b-italian-doc4lm-5gram"
+... )
+```
+
+Poi, carica un dataset (vedi 🤗 Datasets [Quick Start](https://huggingface.co/docs/datasets/quickstart) per maggiori dettagli) sul quale vuoi iterare. Per esempio, carichiamo il dataset [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14):
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="it-IT", split="train") # doctest: +IGNORE_RESULT
+```
+
+Dobbiamo assicurarci che la frequenza di campionamento del set di dati corrisponda alla frequenza di campionamento con cui è stato addestrato `radiogroup-crits/wav2vec2-xls-r-1b-italian-doc4lm-5gram`.
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=riconoscitore_vocale.feature_extractor.sampling_rate))
+```
+
+I file audio vengono caricati automaticamente e ri-campionati quando chiamiamo la colonna "audio".
+Estraiamo i vettori delle forme d'onda grezze delle prime 4 osservazioni e passiamoli come lista alla pipeline:
+
+```py
+>>> risultato = riconoscitore_vocale(dataset[:4]["audio"])
+>>> print([d["text"] for d in risultato])
+['dovrei caricare dei soldi sul mio conto corrente', 'buongiorno e senza vorrei depositare denaro sul mio conto corrente come devo fare per cortesia', 'sì salve vorrei depositare del denaro sul mio conto', 'e buon pomeriggio vorrei depositare dei soldi sul mio conto bancario volleo sapere come posso fare se e posso farlo online ed un altro conto o andandoo tramite bancomut']
+```
+
+Per un dataset più grande dove gli input sono di dimensione maggiore (come nel parlato/audio o nella visione), dovrai passare un generatore al posto di una lista che carica tutti gli input in memoria. Guarda la [documentazione della pipeline](./main_classes/pipelines) per maggiori informazioni.
+
+### Utilizzare un altro modello e tokenizer nella pipeline
+
+La [`pipeline`] può ospitare qualsiasi modello del [Model Hub](https://huggingface.co/models), rendendo semplice l'adattamento della [`pipeline`] per altri casi d'uso. Per esempio, se si vuole un modello capace di trattare testo in francese, usa i tag presenti nel Model Hub in modo da filtrare per ottenere un modello appropriato. Il miglior risultato filtrato restituisce un modello multi-lingua [BERT model](https://huggingface.co/nlptown/bert-base-multilingual-uncased-sentiment) fine-tuned per l'analisi del sentimento. Ottimo, utilizziamo questo modello!
+
+```py
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+```
+
+
+
+Usa [`AutoModelForSequenceClassification`] e [`AutoTokenizer`] per caricare il modello pre-allenato e il suo tokenizer associato (maggiori informazioni su una `AutoClass` in seguito):
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+Usa [`TFAutoModelForSequenceClassification`] e [`AutoTokenizer`] per caricare il modello pre-allenato e il suo tokenizer associato (maggiori informazioni su una `TFAutoClass` in seguito):
+
+```py
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+Poi puoi specificare il modello e il tokenizer nella [`pipeline`], e applicare il `classifier` sul tuo testo obiettivo:
+
+```py
+>>> classifier = pipeline("sentiment-analysis", model=model, tokenizer=tokenizer)
+>>> classifier("Nous sommes très heureux de vous présenter la bibliothèque 🤗 Transformers.")
+[{'label': '5 stars', 'score': 0.7273}]
+```
+
+Se non riesci a trovare un modello per il tuo caso d'uso, dovrai fare fine-tuning di un modello pre-allenato sui tuoi dati. Dai un'occhiata al nostro tutorial [fine-tuning tutorial](./training) per imparare come. Infine, dopo che hai completato il fine-tuning del tuo modello pre-allenato, considera per favore di condividerlo (vedi il tutorial [qui](./model_sharing)) con la comunità sul Model Hub per democratizzare l'NLP! 🤗
+
+## AutoClass
+
+
+
+```py
+>>> pt_batch = tokenizer(
+... ["Siamo molto felici di mostrarti la libreria 🤗 Transformers.", "Speriamo te non la odierai."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="pt",
+... )
+```
+
+
+```py
+>>> tf_batch = tokenizer(
+... ["Siamo molto felici di mostrarti la libreria 🤗 Transformers.", "Speriamo te non la odierai."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="tf",
+... )
+```
+
+
+
+Leggi il tutorial sul [preprocessing](./preprocessing) per maggiori dettagli sulla tokenizzazione.
+
+### AutoModel
+
+
+
+🤗 Transformers fornisce un metodo semplice e unificato per caricare istanze pre-allenate. Questo significa che puoi caricare un [`AutoModel`] come caricheresti un [`AutoTokenizer`]. L'unica differenza è selezionare l'[`AutoModel`] corretto per il compito di interesse. Dato che stai facendo classificazione di testi, o sequenze, carica [`AutoModelForSequenceClassification`]:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+Guarda il [task summary](./task_summary) per sapere quale classe di [`AutoModel`] utilizzare per quale compito.
+
+
+
+Ora puoi passare il tuo lotto di input pre-processati direttamente al modello. Devi solo spacchettare il dizionario aggiungendo `**`:
+
+```py
+>>> pt_outputs = pt_model(**pt_batch)
+```
+
+Il modello produrrà le attivazioni finali nell'attributo `logits`. Applica la funzione softmax a `logits` per ottenere le probabilità:
+
+```py
+>>> from torch import nn
+
+>>> pt_predictions = nn.functional.softmax(pt_outputs.logits, dim=-1)
+>>> print(pt_predictions)
+tensor([[0.0041, 0.0037, 0.0203, 0.2005, 0.7713],
+ [0.3766, 0.3292, 0.1832, 0.0558, 0.0552]], grad_fn=)
+```
+
+
+🤗 Transformers fornisce un metodo semplice e unificato per caricare istanze pre-allenate. Questo significa che puoi caricare un [`TFAutoModel`] come caricheresti un [`AutoTokenizer`]. L'unica differenza è selezionare il [`TFAutoModel`] corretto per il compito di interesse. Dato che stai facendo classificazione di testi, o sequenze, carica [`TFAutoModelForSequenceClassification`]:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> nome_del_modello = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(nome_del_modello)
+```
+
+
+
+Guarda il [task summary](./task_summary) per sapere quale classe di [`AutoModel`] utilizzare per quale compito.
+
+
+
+Ora puoi passare il tuo lotto di input pre-processati direttamente al modello passando le chiavi del dizionario al tensore:
+
+```py
+>>> tf_outputs = tf_model(tf_batch)
+```
+
+Il modello produrrà le attivazioni finali nell'attributo `logits`. Applica la funzione softmax a `logits` per ottenere le probabilità:
+```py
+>>> import tensorflow as tf
+
+>>> tf_predictions = tf.nn.softmax(tf_outputs.logits, axis=-1)
+>>> tf_predictions # doctest: +IGNORE_RESULT
+```
+
+
+
+
+
+Tutti i modelli di 🤗 Transformers (PyTorch e TensorFlow) restituiscono i tensori *prima* della funzione finale
+di attivazione (come la softmax) perché la funzione di attivazione finale viene spesso unita a quella di perdita.
+
+
+
+I modelli sono [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) o [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) standard così puoi utilizzarli all'interno del tuo training loop usuale. Tuttavia, per rendere le cose più semplici, 🤗 Transformers fornisce una classe [`Trainer`] per PyTorch che aggiunge delle funzionalità per l'allenamento distribuito, precisione mista, e altro ancora. Per TensorFlow, puoi utilizzare il metodo `fit` di [Keras](https://keras.io/). Fai riferimento al [tutorial per il training](./training) per maggiori dettagli.
+
+
+
+Gli output del modello di 🤗 Transformers sono delle dataclasses speciali in modo che i loro attributi vengano auto-completati all'interno di un IDE.
+Gli output del modello si comportano anche come una tupla o un dizionario (ad esempio, puoi indicizzare con un intero, una slice o una stringa) nel qual caso gli attributi che sono `None` vengono ignorati.
+
+
+
+### Salva un modello
+
+
+
+Una volta completato il fine-tuning del tuo modello, puoi salvarlo con il suo tokenizer utilizzando [`PreTrainedModel.save_pretrained`]:
+
+```py
+>>> pt_save_directory = "./pt_save_pretrained"
+>>> tokenizer.save_pretrained(pt_save_directory) # doctest: +IGNORE_RESULT
+>>> pt_model.save_pretrained(pt_save_directory)
+```
+
+Quando desideri utilizzare il tuo modello nuovamente, puoi ri-caricarlo con [`PreTrainedModel.from_pretrained`]:
+
+```py
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("./pt_save_pretrained")
+```
+
+
+Una volta completato il fine-tuning del tuo modello, puoi salvarlo con il suo tokenizer utilizzando [`TFPreTrainedModel.save_pretrained`]:
+
+```py
+>>> tf_save_directory = "./tf_save_pretrained"
+>>> tokenizer.save_pretrained(tf_save_directory) # doctest: +IGNORE_RESULT
+>>> tf_model.save_pretrained(tf_save_directory)
+```
+
+Quando desideri utilizzare il tuo modello nuovamente, puoi ri-caricarlo con [`TFPreTrainedModel.from_pretrained`]:
+
+```py
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("./tf_save_pretrained")
+```
+
+
+
+Una caratteristica particolarmente interessante di 🤗 Transformers è la sua abilità di salvare un modello e ri-caricarlo sia come modello di PyTorch che di TensorFlow. I parametri `from_pt` o `from_tf` possono convertire un modello da un framework all'altro:
+
+
+
+
+```py
+>>> from transformers import AutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(pt_save_directory)
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(pt_save_directory, from_pt=True)
+```
+
+
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(tf_save_directory)
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(tf_save_directory, from_tf=True)
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/run_scripts.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/run_scripts.md
new file mode 100644
index 0000000000000000000000000000000000000000..b437efb9fb18f650e1486f5673a0dd8610623964
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/run_scripts.md
@@ -0,0 +1,351 @@
+
+
+# Addestramento con script
+
+Insieme ai [notebooks](./notebooks) 🤗 Transformers, ci sono anche esempi di script che dimostrano come addestrare un modello per un task con [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch), [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow), o [JAX/Flax](https://github.com/huggingface/transformers/tree/main/examples/flax).
+
+Troverai anche script che abbiamo usato nei nostri [progetti di ricerca](https://github.com/huggingface/transformers/tree/main/examples/research_projects) e [precedenti esempi](https://github.com/huggingface/transformers/tree/main/examples/legacy) a cui contribuisce per lo più la comunità. Questi script non sono attivamente mantenuti e richiedono una specifica versione di 🤗 Transformers che sarà molto probabilmente incompatibile con l'ultima versione della libreria.
+
+Non è dato per scontato che gli script di esempio funzionino senza apportare modifiche per ogni problema, bensì potrebbe essere necessario adattare lo script al tuo caso specifico. Per aiutarti in ciò, la maggioranza degli script espone le modalità di pre-processamento dei dati, consentendoti di modificare lo script come preferisci.
+
+Per qualsiasi feature che vorresti implementare in uno script d'esempio, per favore discutine nel [forum](https://discuss.huggingface.co/) o in un'[issue](https://github.com/huggingface/transformers/issues) prima di inviare una Pull Request. Mentre accogliamo con piacere la correzione di bug, è più improbabile che faremo la stessa con una PR che aggiunge funzionalità sacrificando la leggibilità.
+
+Questa guida ti mostrerà come eseguire uno script di esempio relativo al task di summarization in [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization) e [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/summarization). Tutti gli esempi funzioneranno con entrambi i framework a meno che non sia specificato altrimenti.
+
+## Installazione
+
+Per eseguire con successo l'ultima versione degli script di esempio, devi **installare 🤗 Transformers dalla fonte** in un nuovo ambiente virtuale:
+
+```bash
+git clone https://github.com/huggingface/transformers
+cd transformers
+pip install .
+```
+Per le precedenti versioni degli script di esempio, clicca sul pulsante di seguito:
+
+
+ Esempi per versioni precedenti di 🤗 Transformers
+
+
+
+Successivamente, cambia la tua attuale copia di 🤗 Transformers specificandone la versione, ad esempio v3.5.1:
+
+```bash
+git checkout tags/v3.5.1
+```
+
+ Dopo aver configurato correttamente la versione della libreria, naviga nella cartella degli esempi di tua scelta e installa i requisiti:
+
+```bash
+pip install -r requirements.txt
+```
+
+## Esegui uno script
+
+
+
+
+Lo script di esempio scarica e pre-processa un dataset dalla libreria 🤗 [Datasets](https://huggingface.co/docs/datasets/). Successivamente, lo script esegue il fine-tuning su un dataset usando il [Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) su un'architettura che supporta la summarization. Il seguente esempio mostra come eseguire il fine-tuning di [T5-small](https://huggingface.co/google-t5/t5-small) sul dataset [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail). Il modello T5 richiede un parametro addizionale `source_prefix` a causa del modo in cui è stato addestrato. Questo prefisso permette a T5 di sapere che si tratta di un task di summarization.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+Lo script di esempio scarica e pre-processa un dataset dalla libreria 🤗 [Datasets](https://huggingface.co/docs/datasets/). Successivamente, lo script esegue il fine-tuning su un dataset usando Keras su un'architettura che supporta la summarization. Il seguente esempio mostra come eseguire il fine-tuning di [T5-small](https://huggingface.co/google-t5/t5-small) sul dataset [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail). Il modello T5 richiede un parametro addizionale `source_prefix` a causa del modo in cui è stato addestrato. Questo prefisso permette a T5 di sapere che si tratta di un task di summarization.
+
+```bash
+python examples/tensorflow/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## Addestramento distribuito e precisione mista
+
+Il [Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) supporta l'addestramento distribuito e la precisione mista, che significa che puoi anche usarla in uno script. Per abilitare entrambe le funzionalità:
+
+- Aggiunto l'argomento `fp16` per abilitare la precisione mista.
+- Imposta un numero di GPU da usare con l'argomento `nproc_per_node`.
+
+```bash
+torchrun \
+ --nproc_per_node 8 pytorch/summarization/run_summarization.py \
+ --fp16 \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+Gli script TensorFlow utilizzano una [`MirroredStrategy`](https://www.tensorflow.org/guide/distributed_training#mirroredstrategy) per il training distribuito e non devi aggiungere alcun argomento addizionale allo script di training. Lo script TensorFlow userà multiple GPU in modo predefinito se quest'ultime sono disponibili:
+
+## Esegui uno script su TPU
+
+
+
+Le Tensor Processing Units (TPU) sono state progettate per migliorare le prestazioni. PyTorch supporta le TPU con il compilatore per deep learning [XLA](https://www.tensorflow.org/xla) (guarda [questo link](https://github.com/pytorch/xla/blob/master/README.md) per maggiori dettagli). Per usare una TPU, avvia lo script `xla_spawn.py` e usa l'argomento `num_cores` per impostare il numero di core TPU che intendi usare.
+
+```bash
+python xla_spawn.py --num_cores 8 \
+ summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+Le Tensor Processing Units (TPU) sono state progettate per migliorare le prestazioni. Gli script TensorFlow utilizzano una [`TPUStrategy`](https://www.tensorflow.org/guide/distributed_training#tpustrategy) per eseguire l'addestramento su TPU. Per usare una TPU, passa il nome della risorsa TPU all'argomento `tpu`.
+
+```bash
+python run_summarization.py \
+ --tpu name_of_tpu_resource \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## Esegui uno script con 🤗 Accelerate
+
+🤗 [Accelerate](https://huggingface.co/docs/accelerate) è una libreria compatibile solo con PyTorch che offre un metodo unificato per addestrare modelli su diverse tipologie di configurazioni (CPU, multiple GPU, TPU) mantenendo una completa visibilità rispetto al ciclo di training di PyTorch. Assicurati di aver effettuato l'installazione di 🤗 Accelerate, nel caso non lo avessi fatto:
+
+> Nota: dato che Accelerate è in rapido sviluppo, è necessario installare la versione proveniente da git per eseguire gli script:
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+Invece che usare lo script `run_summarization.py`, devi usare lo script `run_summarization_no_trainer.py`. Gli script supportati in 🤗 Accelerate avranno un file chiamato `task_no_trainer.py` nella rispettiva cartella. Per iniziare, esegui il seguente comando per creare e salvare un file di configurazione:
+
+```bash
+accelerate config
+```
+
+Testa la tua configurazione per assicurarti della sua correttezza:
+
+```bash
+accelerate test
+```
+
+Ora sei pronto per avviare l'addestramento:
+
+```bash
+accelerate launch run_summarization_no_trainer.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir ~/tmp/tst-summarization
+```
+
+## Uso di un dataset personalizzato
+
+Lo script di summarization supporta dataset personalizzati purché siano file CSV o JSON Line. Quando usi il tuo dataset, devi specificare diversi argomenti aggiuntivi:
+
+- `train_file` e `validation_file` specificano dove si trovano i file di addestramento e validazione.
+- `text_column` è il file di input da riassumere.
+- `summary_column` è il file di destinazione per l'output.
+
+Uno script di summarization usando un dataset personalizzato sarebbe simile a questo:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --train_file path_to_csv_or_jsonlines_file \
+ --validation_file path_to_csv_or_jsonlines_file \
+ --text_column text_column_name \
+ --summary_column summary_column_name \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --overwrite_output_dir \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --predict_with_generate
+```
+
+## Testare uno script
+
+È spesso una buona idea avviare il tuo script su un numero inferiore di esempi tratti dal dataset, per assicurarti che tutto funzioni come previsto prima di eseguire lo script sull'intero dataset, che potrebbe necessitare di ore. Usa i seguenti argomenti per limitare il dataset ad un massimo numero di esempi:
+
+- `max_train_samples`
+- `max_eval_samples`
+- `max_predict_samples`
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --max_train_samples 50 \
+ --max_eval_samples 50 \
+ --max_predict_samples 50 \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+Non tutti gli esempi di script supportano l'argomento `max_predict_samples`. Se non sei sicuro circa il supporto di questo argomento da parte del tuo script, aggiungi l'argomento `-h` per controllare:
+
+```bash
+examples/pytorch/summarization/run_summarization.py -h
+```
+
+## Riavviare addestramento da un checkpoint
+
+Un'altra utile opzione è riavviare un addestramento da un checkpoint precedente. Questo garantirà che tu possa riprendere da dove hai interrotto senza ricominciare se l'addestramento viene interrotto. Ci sono due metodi per riavviare l'addestramento da un checkpoint:
+
+Il primo metodo usa l'argomento `output_dir previous_output_dir` per riavviare l'addestramento dall'ultima versione del checkpoint contenuto in `output_dir`. In questo caso, dovresti rimuovere `overwrite_output_dir`:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --output_dir previous_output_dir \
+ --predict_with_generate
+```
+
+Il secondo metodo usa l'argomento `resume_from_checkpoint path_to_specific_checkpoint` per riavviare un addestramento da una specifica cartella di checkpoint.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --resume_from_checkpoint path_to_specific_checkpoint \
+ --predict_with_generate
+```
+
+## Condividi il tuo modello
+
+Tutti gli script possono caricare il tuo modello finale al [Model Hub](https://huggingface.co/models). Prima di iniziare, assicurati di aver effettuato l'accesso su Hugging Face:
+
+```bash
+huggingface-cli login
+```
+
+Poi, aggiungi l'argomento `push_to_hub` allo script. Questo argomento consentirà di creare un repository con il tuo username Hugging Face e la cartella specificata in `output_dir`.
+
+Per dare uno specifico nome al repository, usa l'argomento `push_to_hub_model_id`. Il repository verrà automaticamente elencata sotto al tuo namespace.
+
+Il seguente esempio mostra come caricare un modello specificando il nome del repository:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --push_to_hub \
+ --push_to_hub_model_id finetuned-t5-cnn_dailymail \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/serialization.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/serialization.md
new file mode 100644
index 0000000000000000000000000000000000000000..974aee0d81cae0425fbd6a6fa3052dd5c2c25282
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/serialization.md
@@ -0,0 +1,676 @@
+
+
+# Esporta modelli 🤗 Transformers
+
+Se devi implementare 🤗 modelli Transformers in ambienti di produzione, noi
+consigliamo di esportarli in un formato serializzato che può essere caricato ed eseguito
+su runtime e hardware specializzati. In questa guida ti mostreremo come farlo
+esporta 🤗 Modelli Transformers in due formati ampiamente utilizzati: ONNX e TorchScript.
+
+Una volta esportato, un modello può essere ottimizato per l'inferenza tramite tecniche come
+la quantizzazione e soppressione. Se sei interessato a ottimizzare i tuoi modelli per l'esecuzione
+con la massima efficienza, dai un'occhiata a [🤗 Optimum
+library](https://github.com/huggingface/optimum).
+
+## ONNX
+
+Il progetto [ONNX (Open Neural Network eXchange)](http://onnx.ai) Il progetto onnx è un open
+standard che definisce un insieme comune di operatori e un formato di file comune a
+rappresentano modelli di deep learning in un'ampia varietà di framework, tra cui
+PyTorch e TensorFlow. Quando un modello viene esportato nel formato ONNX, questi
+operatori sono usati per costruire un grafico computazionale (often called an
+_intermediate representation_) che rappresenta il flusso di dati attraverso la
+rete neurale.
+
+Esponendo un grafico con operatori e tipi di dati standardizzati, ONNX rende
+più facile passare da un framework all'altro. Ad esempio, un modello allenato in PyTorch può
+essere esportato in formato ONNX e quindi importato in TensorFlow (e viceversa).
+
+🤗 Transformers fornisce un pacchetto `transformers.onnx` che ti consente di
+convertire i checkpoint del modello in un grafico ONNX sfruttando gli oggetti di configurazione.
+Questi oggetti di configurazione sono già pronti per una serie di architetture di modelli,
+e sono progettati per essere facilmente estensibili ad altre architetture.
+
+Le configurazioni pronte includono le seguenti architetture:
+
+
+
+- ALBERT
+- BART
+- BEiT
+- BERT
+- BigBird
+- BigBird-Pegasus
+- Blenderbot
+- BlenderbotSmall
+- CamemBERT
+- ConvBERT
+- Data2VecText
+- Data2VecVision
+- DeiT
+- DistilBERT
+- ELECTRA
+- FlauBERT
+- GPT Neo
+- GPT-J
+- I-BERT
+- LayoutLM
+- M2M100
+- Marian
+- mBART
+- MobileBERT
+- OpenAI GPT-2
+- Perceiver
+- PLBart
+- RoBERTa
+- RoFormer
+- SqueezeBERT
+- T5
+- ViT
+- XLM
+- XLM-RoBERTa
+- XLM-RoBERTa-XL
+
+Nelle prossime due sezioni, ti mostreremo come:
+
+* Esporta un modello supportato usando il pacchetto `transformers.onnx`.
+* Esporta un modello personalizzato per un'architettura non supportata.
+
+### Esportazione di un modello in ONNX
+
+Per esportare un modello 🤗 Transformers in ONNX, dovrai prima installarne alcune
+dipendenze extra:
+
+```bash
+pip install transformers[onnx]
+```
+
+Il pacchetto `transformers.onnx` può essere usato come modulo Python:
+
+```bash
+python -m transformers.onnx --help
+
+usage: Hugging Face Transformers ONNX exporter [-h] -m MODEL [--feature {causal-lm, ...}] [--opset OPSET] [--atol ATOL] output
+
+positional arguments:
+ output Path indicating where to store generated ONNX model.
+
+optional arguments:
+ -h, --help show this help message and exit
+ -m MODEL, --model MODEL
+ Model ID on huggingface.co or path on disk to load model from.
+ --feature {causal-lm, ...}
+ The type of features to export the model with.
+ --opset OPSET ONNX opset version to export the model with.
+ --atol ATOL Absolute difference tolerance when validating the model.
+```
+
+L'esportazione di un checkpoint utilizzando una configurazione già pronta può essere eseguita come segue:
+
+```bash
+python -m transformers.onnx --model=distilbert/distilbert-base-uncased onnx/
+```
+
+che dovrebbe mostrare i seguenti log:
+
+```bash
+Validating ONNX model...
+ -[✓] ONNX model output names match reference model ({'last_hidden_state'})
+ - Validating ONNX Model output "last_hidden_state":
+ -[✓] (2, 8, 768) matches (2, 8, 768)
+ -[✓] all values close (atol: 1e-05)
+All good, model saved at: onnx/model.onnx
+```
+
+Questo esporta un grafico ONNX del checkpoint definito dall'argomento `--model`.
+In questo esempio è `distilbert/distilbert-base-uncased`, ma può essere qualsiasi checkpoint
+Hugging Face Hub o uno memorizzato localmente.
+
+Il file risultante `model.onnx` può quindi essere eseguito su uno dei [tanti
+acceleratori](https://onnx.ai/supported-tools.html#deployModel) che supportano il
+lo standard ONNX. Ad esempio, possiamo caricare ed eseguire il modello con [ONNX
+Runtime](https://onnxruntime.ai/) come segue:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> from onnxruntime import InferenceSession
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> session = InferenceSession("onnx/model.onnx")
+>>> # ONNX Runtime expects NumPy arrays as input
+>>> inputs = tokenizer("Using DistilBERT with ONNX Runtime!", return_tensors="np")
+>>> outputs = session.run(output_names=["last_hidden_state"], input_feed=dict(inputs))
+```
+
+I nomi di output richiesti (cioè `["last_hidden_state"]`) possono essere ottenuti
+dando un'occhiata alla configurazione ONNX di ogni modello. Ad esempio, per
+DistilBERT abbiamo:
+
+```python
+>>> from transformers.models.distilbert import DistilBertConfig, DistilBertOnnxConfig
+
+>>> config = DistilBertConfig()
+>>> onnx_config = DistilBertOnnxConfig(config)
+>>> print(list(onnx_config.outputs.keys()))
+["last_hidden_state"]
+```
+
+Il processo è identico per i checkpoint TensorFlow sull'hub. Ad esempio, noi
+possiamo esportare un checkpoint TensorFlow puro da [Keras
+organizzazione](https://huggingface.co/keras-io) come segue:
+
+```bash
+python -m transformers.onnx --model=keras-io/transformers-qa onnx/
+```
+
+Per esportare un modello memorizzato localmente, devi disporre dei pesi del modello
+e file tokenizer memorizzati in una directory. Ad esempio, possiamo caricare e salvare un
+checkpoint come segue:
+
+
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> # Load tokenizer and PyTorch weights form the Hub
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+>>> # Save to disk
+>>> tokenizer.save_pretrained("local-pt-checkpoint")
+>>> pt_model.save_pretrained("local-pt-checkpoint")
+```
+
+Una volta salvato il checkpoint, possiamo esportarlo su ONNX puntando l'argomento `--model`
+del pacchetto `transformers.onnx` nella directory desiderata:
+
+```bash
+python -m transformers.onnx --model=local-pt-checkpoint onnx/
+```
+
+
+```python
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> # Load tokenizer and TensorFlow weights from the Hub
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+>>> # Save to disk
+>>> tokenizer.save_pretrained("local-tf-checkpoint")
+>>> tf_model.save_pretrained("local-tf-checkpoint")
+```
+
+Once the checkpoint is saved, we can export it to ONNX by pointing the `--model`
+argument of the `transformers.onnx` package to the desired directory:
+
+```bash
+python -m transformers.onnx --model=local-tf-checkpoint onnx/
+```
+
+
+
+### Selezione delle caratteristiche per diverse topologie di modello
+
+Ogni configurazione già pronta viene fornita con una serie di _caratteristiche_ che ti consentono di
+esportare modelli per diversi tipi di topologie o attività. Come mostrato nella tabella
+di seguito, ogni caratteristica è associata a una diversa Auto Class:
+
+| Caratteristica | Auto Class |
+| ------------------------------------ | ------------------------------------ |
+| `causal-lm`, `causal-lm-with-past` | `AutoModelForCausalLM` |
+| `default`, `default-with-past` | `AutoModel` |
+| `masked-lm` | `AutoModelForMaskedLM` |
+| `question-answering` | `AutoModelForQuestionAnswering` |
+| `seq2seq-lm`, `seq2seq-lm-with-past` | `AutoModelForSeq2SeqLM` |
+| `sequence-classification` | `AutoModelForSequenceClassification` |
+| `token-classification` | `AutoModelForTokenClassification` |
+
+Per ciascuna configurazione, puoi trovare l'elenco delle funzionalità supportate tramite il
+`FeaturesManager`. Ad esempio, per DistilBERT abbiamo:
+
+```python
+>>> from transformers.onnx.features import FeaturesManager
+
+>>> distilbert_features = list(FeaturesManager.get_supported_features_for_model_type("distilbert").keys())
+>>> print(distilbert_features)
+["default", "masked-lm", "causal-lm", "sequence-classification", "token-classification", "question-answering"]
+```
+
+Puoi quindi passare una di queste funzionalità all'argomento `--feature` nel
+pacchetto `transformers.onnx`. Ad esempio, per esportare un modello di classificazione del testo
+possiamo scegliere un modello ottimizzato dall'Hub ed eseguire:
+
+```bash
+python -m transformers.onnx --model=distilbert/distilbert-base-uncased-finetuned-sst-2-english \
+ --feature=sequence-classification onnx/
+```
+
+che visualizzerà i seguenti registri:
+
+```bash
+Validating ONNX model...
+ -[✓] ONNX model output names match reference model ({'logits'})
+ - Validating ONNX Model output "logits":
+ -[✓] (2, 2) matches (2, 2)
+ -[✓] all values close (atol: 1e-05)
+All good, model saved at: onnx/model.onnx
+```
+
+Puoi notare che in questo caso, i nomi di output del modello ottimizzato sono
+`logits` invece di `last_hidden_state` che abbiamo visto con il
+checkpoint `distilbert/distilbert-base-uncased` precedente. Questo è previsto dal
+modello ottimizato visto che ha una testa di e.
+
+
+
+Le caratteristiche che hanno un suffisso `wtih-past` (ad es. `causal-lm-with-past`)
+corrispondono a topologie di modello con stati nascosti precalcolati (chiave e valori
+nei blocchi di attenzione) che possono essere utilizzati per la decodifica autoregressiva veloce.
+
+
+
+
+### Esportazione di un modello per un'architettura non supportata
+
+Se desideri esportare un modello la cui architettura non è nativamente supportata dalla
+libreria, ci sono tre passaggi principali da seguire:
+
+1. Implementare una configurazione ONNX personalizzata.
+2. Esportare il modello in ONNX.
+3. Convalidare gli output di PyTorch e dei modelli esportati.
+
+In questa sezione, vedremo come DistilBERT è stato implementato per mostrare cosa è
+coinvolto in ogni passaggio.
+
+#### Implementazione di una configurazione ONNX personalizzata
+
+Iniziamo con l'oggetto di configurazione ONNX. Forniamo tre classi
+astratte da cui ereditare, a seconda del tipo di archittettura
+del modello che desideri esportare:
+
+* I modelli basati su encoder ereditano da [`~onnx.config.OnnxConfig`]
+* I modelli basati su decoder ereditano da [`~onnx.config.OnnxConfigWithPast`]
+* I modelli encoder-decoder ereditano da[`~onnx.config.OnnxSeq2SeqConfigWithPast`]
+
+
+
+Un buon modo per implementare una configurazione ONNX personalizzata è guardare l'implementazione
+esistente nel file `configuration_.py` di un'architettura simile.
+
+
+
+Poiché DistilBERT è un modello basato su encoder, la sua configurazione eredita da
+`OnnxConfig`:
+
+```python
+>>> from typing import Mapping, OrderedDict
+>>> from transformers.onnx import OnnxConfig
+
+
+>>> class DistilBertOnnxConfig(OnnxConfig):
+... @property
+... def inputs(self) -> Mapping[str, Mapping[int, str]]:
+... return OrderedDict(
+... [
+... ("input_ids", {0: "batch", 1: "sequence"}),
+... ("attention_mask", {0: "batch", 1: "sequence"}),
+... ]
+... )
+```
+
+Ogni oggetto di configurazione deve implementare la proprietà `inputs` e restituire una
+mappatura, dove ogni chiave corrisponde a un input previsto e ogni valore
+indica l'asse di quell'input. Per DistilBERT, possiamo vedere che sono richiesti
+due input: `input_ids` e `attention_mask`. Questi inputs hanno la stessa forma di
+`(batch_size, sequence_length)` per questo motivo vediamo gli stessi assi usati nella
+configurazione.
+
+
+
+Puoi notare che la proprietà `inputs` per `DistilBertOnnxConfig` restituisce un
+`OrdinatoDict`. Ciò garantisce che gli input corrispondano alla loro posizione
+relativa all'interno del metodo `PreTrainedModel.forward()` durante il tracciamento del grafico.
+Raccomandiamo di usare un `OrderedDict` per le proprietà `inputs` e `outputs`
+quando si implementano configurazioni ONNX personalizzate.
+
+
+
+Dopo aver implementato una configurazione ONNX, è possibile istanziarla
+fornendo alla configurazione del modello base come segue:
+
+```python
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased")
+>>> onnx_config = DistilBertOnnxConfig(config)
+```
+
+L'oggetto risultante ha diverse proprietà utili. Ad esempio è possibile visualizzare il
+Set operatore ONNX che verrà utilizzato durante l'esportazione:
+
+```python
+>>> print(onnx_config.default_onnx_opset)
+11
+```
+
+È inoltre possibile visualizzare gli output associati al modello come segue:
+
+```python
+>>> print(onnx_config.outputs)
+OrderedDict([("last_hidden_state", {0: "batch", 1: "sequence"})])
+```
+
+Puoi notare che la proprietà degli output segue la stessa struttura degli input; esso
+restituisce un `OrderedDict` di output con nome e le loro forme. La struttura di output
+è legato alla scelta della funzione con cui viene inizializzata la configurazione.
+Per impostazione predefinita, la configurazione ONNX viene inizializzata con la funzione 'predefinita'
+che corrisponde all'esportazione di un modello caricato con la classe `AutoModel`. Se tu
+desideri esportare una topologia di modello diversa, è sufficiente fornire una funzionalità diversa a
+l'argomento `task` quando inizializzi la configurazione ONNX. Ad esempio, se
+volevamo esportare DistilBERT con una testa di classificazione per sequenze, potremmo
+usare:
+
+```python
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased")
+>>> onnx_config_for_seq_clf = DistilBertOnnxConfig(config, task="sequence-classification")
+>>> print(onnx_config_for_seq_clf.outputs)
+OrderedDict([('logits', {0: 'batch'})])
+```
+
+
+
+Tutte le proprietà e i metodi di base associati a [`~onnx.config.OnnxConfig`] e le
+altre classi di configurazione possono essere sovrascritte se necessario. Guarda
+[`BartOnnxConfig`] per un esempio avanzato.
+
+
+
+#### Esportazione del modello
+
+Una volta implementata la configurazione ONNX, il passaggio successivo consiste nell'esportare il
+modello. Qui possiamo usare la funzione `export()` fornita dal
+pacchetto `transformers.onnx`. Questa funzione prevede la configurazione ONNX, insieme
+con il modello base e il tokenizer e il percorso per salvare il file esportato:
+
+```python
+>>> from pathlib import Path
+>>> from transformers.onnx import export
+>>> from transformers import AutoTokenizer, AutoModel
+
+>>> onnx_path = Path("model.onnx")
+>>> model_ckpt = "distilbert/distilbert-base-uncased"
+>>> base_model = AutoModel.from_pretrained(model_ckpt)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_ckpt)
+
+>>> onnx_inputs, onnx_outputs = export(tokenizer, base_model, onnx_config, onnx_config.default_onnx_opset, onnx_path)
+```
+
+Gli `onnx_inputs` e `onnx_outputs` restituiti dalla funzione `export()` sono
+liste di chiavi definite nelle proprietà di `input` e `output` della
+configurazione. Una volta esportato il modello, puoi verificare che il modello sia ben
+formato come segue:
+
+```python
+>>> import onnx
+
+>>> onnx_model = onnx.load("model.onnx")
+>>> onnx.checker.check_model(onnx_model)
+```
+
+
+
+Se il tuo modello è più largo di 2 GB, vedrai che molti file aggiuntivi sono
+creati durante l'esportazione. Questo è _previsto_ perché ONNX utilizza [Protocol
+Buffer](https://developers.google.com/protocol-buffers/) per memorizzare il modello e
+questi hanno un limite di dimensione 2 GB. Vedi la [Documentazione
+ONNX](https://github.com/onnx/onnx/blob/master/docs/ExternalData.md)
+per istruzioni su come caricare modelli con dati esterni.
+
+
+
+#### Convalida degli output del modello
+
+Il passaggio finale consiste nel convalidare gli output dal modello di base e quello esportato
+corrispondere entro una soglia di tolleranza assoluta. Qui possiamo usare la
+Funzione `validate_model_outputs()` fornita dal pacchetto `transformers.onnx`
+come segue:
+
+```python
+>>> from transformers.onnx import validate_model_outputs
+
+>>> validate_model_outputs(
+... onnx_config, tokenizer, base_model, onnx_path, onnx_outputs, onnx_config.atol_for_validation
+... )
+```
+
+Questa funzione usa il metodo `OnnxConfig.generate_dummy_inputs()` per generare
+input per il modello di base e quello esportato e la tolleranza assoluta può essere
+definita nella configurazione. Generalmente troviamo una corrispondenza numerica nell'intervallo da 1e-6
+a 1e-4, anche se è probabile che qualsiasi cosa inferiore a 1e-3 vada bene.
+
+### Contribuire con una nuova configurazione a 🤗 Transformers
+
+Stiamo cercando di espandere l'insieme di configurazioni già pronte e di accettare
+contributi della community! Se vuoi contribuire con la tua aggiunta
+nella libreria, dovrai:
+
+* Implementare la configurazione ONNX nella corrispondente `configuration file
+_.py`
+* Includere l'architettura del modello e le funzioni corrispondenti in [`~onnx.features.FeatureManager`]
+* Aggiungere la tua architettura del modello ai test in `test_onnx_v2.py`
+
+Scopri come stato contribuito la configurazione per [IBERT](https://github.com/huggingface/transformers/pull/14868/files) per
+avere un'idea di cosa è coinvolto.
+
+## TorchScript
+
+
+
+Questo è l'inizio dei nostri esperimenti con TorchScript e stiamo ancora esplorando le sue capacità con
+modelli con variable-input-size. È una nostra priorità e approfondiremo le nostre analisi nelle prossime versioni,
+con più esempi di codici, un'implementazione più flessibile e benchmark che confrontano i codici basati su Python con quelli compilati con
+TorchScript.
+
+
+
+Secondo la documentazione di Pytorch: "TorchScript è un modo per creare modelli serializzabili e ottimizzabili da codice
+Pytorch". I due moduli di Pytorch [JIT e TRACE](https://pytorch.org/docs/stable/jit.html) consentono allo sviluppatore di esportare
+il loro modello da riutilizzare in altri programmi, come i programmi C++ orientati all'efficienza.
+
+Abbiamo fornito un'interfaccia che consente l'esportazione di modelli 🤗 Transformers in TorchScript in modo che possano essere riutilizzati
+in un ambiente diverso rispetto a un programma Python basato su Pytorch. Qui spieghiamo come esportare e utilizzare i nostri modelli utilizzando
+TorchScript.
+
+Esportare un modello richiede due cose:
+
+- Un passaggio in avanti con input fittizzi.
+- Istanziazione del modello con flag `torchscript`.
+
+Queste necessità implicano diverse cose a cui gli sviluppatori dovrebbero prestare attenzione. Questi dettagli mostrati sotto.
+
+### Flag TorchScript e pesi legati
+
+Questo flag è necessario perché la maggior parte dei modelli linguistici in questo repository hanno pesi legati tra il loro
+strato "Embedding" e lo strato "Decoding". TorchScript non consente l'esportazione di modelli che hanno pesi
+legati, quindi è necessario prima slegare e clonare i pesi.
+
+Ciò implica che i modelli istanziati con il flag `torchscript` hanno il loro strato `Embedding` e strato `Decoding`
+separato, il che significa che non dovrebbero essere addestrati in futuro. L'allenamento de-sincronizza i due
+strati, portando a risultati inaspettati.
+
+Questo non è il caso per i modelli che non hanno una testa del modello linguistico, poiché quelli non hanno pesi legati. Questi modelli
+può essere esportato in sicurezza senza il flag `torchscript`.
+
+### Input fittizi e standard lengths
+
+Gli input fittizzi sono usati per fare un modello passaggio in avanti . Mentre i valori degli input si propagano attraverso i strati,
+Pytorch tiene traccia delle diverse operazioni eseguite su ciascun tensore. Queste operazioni registrate vengono quindi utilizzate per
+creare la "traccia" del modello.
+
+La traccia viene creata relativamente alle dimensioni degli input. È quindi vincolato dalle dimensioni dell'input
+fittizio e non funzionerà per altre lunghezze di sequenza o dimensioni batch. Quando si proverà con una dimensione diversa, ci sarà errore
+come:
+
+`La dimensione espansa del tensore (3) deve corrispondere alla dimensione esistente (7) nella dimensione non singleton 2`
+
+will be raised. Si consiglia pertanto di tracciare il modello con una dimensione di input fittizia grande almeno quanto il più grande
+input che verrà fornito al modello durante l'inferenza. È possibile eseguire il padding per riempire i valori mancanti. Il modello
+sarà tracciato con una grande dimensione di input, tuttavia, anche le dimensioni della diverse matrici saranno grandi,
+risultando in più calcoli.
+
+Si raccomanda di prestare attenzione al numero totale di operazioni eseguite su ciascun input e di seguire da vicino le prestazioni
+durante l'esportazione di modelli di sequenza-lunghezza variabili.
+
+### Usare TorchSscript in Python
+
+Di seguito è riportato un esempio, che mostra come salvare, caricare modelli e come utilizzare la traccia per l'inferenza.
+
+#### Salvare un modello
+
+Questo frammento di codice mostra come usare TorchScript per esportare un `BertModel`. Qui il `BertModel` è istanziato secondo
+una classe `BertConfig` e quindi salvato su disco con il nome del file `traced_bert.pt`
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+
+enc = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+
+# Tokenizing input text
+text = "[CLS] Who was Jim Henson ? [SEP] Jim Henson was a puppeteer [SEP]"
+tokenized_text = enc.tokenize(text)
+
+# Masking one of the input tokens
+masked_index = 8
+tokenized_text[masked_index] = "[MASK]"
+indexed_tokens = enc.convert_tokens_to_ids(tokenized_text)
+segments_ids = [0, 0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1]
+
+# Creating a dummy input
+tokens_tensor = torch.tensor([indexed_tokens])
+segments_tensors = torch.tensor([segments_ids])
+dummy_input = [tokens_tensor, segments_tensors]
+
+# Initializing the model with the torchscript flag
+# Flag set to True even though it is not necessary as this model does not have an LM Head.
+config = BertConfig(
+ vocab_size_or_config_json_file=32000,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ torchscript=True,
+)
+
+# Instantiating the model
+model = BertModel(config)
+
+# The model needs to be in evaluation mode
+model.eval()
+
+# If you are instantiating the model with *from_pretrained* you can also easily set the TorchScript flag
+model = BertModel.from_pretrained("google-bert/bert-base-uncased", torchscript=True)
+
+# Creating the trace
+traced_model = torch.jit.trace(model, [tokens_tensor, segments_tensors])
+torch.jit.save(traced_model, "traced_bert.pt")
+```
+
+#### Caricare un modello
+
+Questo frammento di codice mostra come caricare il `BertModel` che era stato precedentemente salvato su disco con il nome `traced_bert.pt`.
+Stiamo riutilizzando il `dummy_input` precedentemente inizializzato.
+
+```python
+loaded_model = torch.jit.load("traced_bert.pt")
+loaded_model.eval()
+
+all_encoder_layers, pooled_output = loaded_model(*dummy_input)
+```
+
+#### Utilizzare un modello tracciato per l'inferenza
+
+Usare il modello tracciato per l'inferenza è semplice come usare il suo metodo dunder `__call__`:
+
+```python
+traced_model(tokens_tensor, segments_tensors)
+```
+
+### Implementare modelli HuggingFace TorchScript su AWS utilizzando Neuron SDK
+
+AWS ha introdotto [Amazon EC2 Inf1](https://aws.amazon.com/ec2/instance-types/inf1/)
+famiglia di istanze per l'inferenza di machine learning a basso costo e ad alte prestazioni nel cloud.
+Le istanze Inf1 sono alimentate dal chip AWS Inferentia, un acceleratore hardware personalizzato,
+specializzato in carichi di lavoro di inferenza di deep learning.
+[AWS Neuron](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/#)
+è l'SDK per Inferentia che supporta il tracciamento e l'ottimizzazione dei modelli transformers per
+distribuzione su Inf1. L'SDK Neuron fornisce:
+
+
+1. API di facile utilizzo con una riga di modifica del codice per tracciare e ottimizzare un modello TorchScript per l'inferenza nel cloud.
+2. Ottimizzazioni delle prestazioni pronte all'uso per [miglioramento dei costi-prestazioni](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/benchmark/>)
+3. Supporto per i modelli di trasformatori HuggingFace costruiti con [PyTorch](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/bert_tutorial/tutorial_pretrained_bert.html)
+ o [TensorFlow](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/tensorflow/huggingface_bert/huggingface_bert.html).
+
+#### Implicazioni
+
+Modelli Transformers basati su architettura [BERT (Bidirectional Encoder Representations from Transformers)](https://huggingface.co/docs/transformers/main/model_doc/bert),
+o sue varianti come [distilBERT](https://huggingface.co/docs/transformers/main/model_doc/distilbert)
+e [roBERTa](https://huggingface.co/docs/transformers/main/model_doc/roberta)
+funzioneranno meglio su Inf1 per attività non generative come la question answering estrattive,
+Classificazione della sequenza, Classificazione dei token. In alternativa, generazione di testo
+le attività possono essere adattate per essere eseguite su Inf1, secondo questo [tutorial AWS Neuron MarianMT](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/transformers-marianmt.html).
+Ulteriori informazioni sui modelli che possono essere convertiti fuori dagli schemi su Inferentia possono essere
+trovati nella [sezione Model Architecture Fit della documentazione Neuron](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/models/models-inferentia.html#models-inferentia).
+
+#### Dipendenze
+
+L'utilizzo di AWS Neuron per convertire i modelli richiede le seguenti dipendenze e l'ambiente:
+
+* A [Neuron SDK environment](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/neuron-frameworks/pytorch-neuron/index.html#installation-guide),
+ which comes pre-configured on [AWS Deep Learning AMI](https://docs.aws.amazon.com/dlami/latest/devguide/tutorial-inferentia-launching.html).
+
+#### Convertire un modello per AWS Neuron
+
+Usando lo stesso script come in [Usando TorchScipt in Python](https://huggingface.co/docs/transformers/main/en/serialization#using-torchscript-in-python)
+per tracciare un "BertModel", importi l'estensione del framework `torch.neuron` per accedere
+i componenti di Neuron SDK tramite un'API Python.
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+import torch.neuron
+```
+E modificare solo la riga di codice di traccia
+
+Da:
+
+```python
+torch.jit.trace(model, [tokens_tensor, segments_tensors])
+```
+
+A:
+
+```python
+torch.neuron.trace(model, [token_tensor, segments_tensors])
+```
+
+Questa modifica consente a Neuron SDK di tracciare il modello e ottimizzarlo per l'esecuzione nelle istanze Inf1.
+
+Per ulteriori informazioni sulle funzionalità, gli strumenti, i tutorial di esempi e gli ultimi aggiornamenti di AWS Neuron SDK,
+consultare la [documentazione AWS NeuronSDK](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/index.html).
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/training.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/training.md
new file mode 100644
index 0000000000000000000000000000000000000000..21008a92bf7c6f0e091d1573791c06540dfeae13
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/it/training.md
@@ -0,0 +1,376 @@
+
+
+# Fine-tuning di un modello pre-addestrato
+
+[[open-in-colab]]
+
+Ci sono benefici significativi nell'usare un modello pre-addestrato. Si riducono i costi computazionali, l'impronta di carbonio e ti consente di usare modelli stato dell'arte senza doverli addestrare da zero. 🤗 Transformers consente l'accesso a migliaia di modelli pre-addestrati per un'ampia gamma di compiti. Quando usi un modello pre-addestrato, lo alleni su un dataset specifico per il tuo compito. Questo è conosciuto come fine-tuning, una tecnica di addestramento incredibilmente potente. In questa esercitazione, potrai fare il fine-tuning di un modello pre-addestrato, con un framework di deep learning a tua scelta:
+
+* Fine-tuning di un modello pre-addestrato con 🤗 Transformers [`Trainer`].
+* Fine-tuning di un modello pre-addestrato in TensorFlow con Keras.
+* Fine-tuning di un modello pre-addestrato con PyTorch.
+
+
+
+
+
+Potresti vedere un warning dato che alcuni dei pesi pre-addestrati non sono stati utilizzati e altri pesi sono stati inizializzati casualmente. Non preoccuparti, è completamente normale! L'head pre-addestrata del modello BERT viene scartata e rimpiazzata da una classification head inizializzata casualmente. Farai il fine-tuning di questa nuova head del modello sul tuo compito di classificazione, trasferendogli la conoscenza del modello pre-addestrato.
+
+
+
+### Iperparametri per il training
+
+Successivamente, crea una classe [`TrainingArguments`] contenente tutti gli iperparametri che si possono regore nonché le variabili per attivare le differenti opzioni di addestramento. Per questa esercitazione puoi iniziare con gli [iperparametri](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments) di ddestramento predefiniti, ma sentiti libero di sperimentare per trovare la configurazione ottimale per te.
+
+Specifica dove salvare i checkpoints del tuo addestramento:
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(output_dir="test_trainer")
+```
+
+### Metriche
+
+[`Trainer`] non valuta automaticamente le performance del modello durante l'addestramento. Dovrai passare a [`Trainer`] una funzione che calcola e restituisce le metriche. La libreria 🤗 Datasets mette a disposizione una semplice funzione [`accuracy`](https://huggingface.co/metrics/accuracy) che puoi caricare con la funzione `load_metric` (guarda questa [esercitazione](https://huggingface.co/docs/datasets/metrics) per maggiori informazioni):
+
+```py
+>>> import numpy as np
+>>> from datasets import load_metric
+
+>>> metric = load_metric("accuracy")
+```
+
+Richiama `compute` su `metric` per calcolare l'accuratezza delle tue previsioni. Prima di passare le tue previsioni a `compute`, hai bisogno di convertirle in logits (ricorda che tutti i modelli 🤗 Transformers restituiscono logits):
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... predictions = np.argmax(logits, axis=-1)
+... return metric.compute(predictions=predictions, references=labels)
+```
+
+Se preferisci monitorare le tue metriche di valutazione durante il fine-tuning, specifica il parametro `eval_strategy` nei tuoi training arguments per restituire le metriche di valutazione ad ogni epoca di addestramento:
+
+```py
+>>> from transformers import TrainingArguments, Trainer
+
+>>> training_args = TrainingArguments(output_dir="test_trainer", eval_strategy="epoch")
+```
+
+### Trainer
+
+Crea un oggetto [`Trainer`] col tuo modello, training arguments, dataset di training e test, e funzione di valutazione:
+
+```py
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... )
+```
+
+Poi metti a punto il modello richiamando [`~transformers.Trainer.train`]:
+
+```py
+>>> trainer.train()
+```
+
+
+
+
+[`Trainer`] usa [`DataCollatorWithPadding`] in maniera predefinita in modo da non dover specificare esplicitamente un collettore di dati.
+
+
+
+Successivamente, converti i datasets tokenizzati in TensorFlow datasets con il metodo [`to_tf_dataset`](https://huggingface.co/docs/datasets/package_reference/main_classes.html#datasets.Dataset.to_tf_dataset). Specifica il tuo input in `columns` e le tue etichette in `label_cols`:
+
+```py
+>>> tf_train_dataset = small_train_dataset.to_tf_dataset(
+... columns=["attention_mask", "input_ids", "token_type_ids"],
+... label_cols=["labels"],
+... shuffle=True,
+... collate_fn=data_collator,
+... batch_size=8,
+... )
+
+>>> tf_validation_dataset = small_eval_dataset.to_tf_dataset(
+... columns=["attention_mask", "input_ids", "token_type_ids"],
+... label_cols=["labels"],
+... shuffle=False,
+... collate_fn=data_collator,
+... batch_size=8,
+... )
+```
+
+### Compilazione e addestramento
+
+Carica un modello TensorFlow col numero atteso di etichette:
+
+```py
+>>> import tensorflow as tf
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-cased", num_labels=5)
+```
+
+Poi compila e fai il fine-tuning del tuo modello usando [`fit`](https://keras.io/api/models/model_training_apis/) come faresti con qualsiasi altro modello di Keras:
+
+```py
+>>> model.compile(
+... optimizer=tf.keras.optimizers.Adam(learning_rate=5e-5),
+... loss=tf.keras.losses.SparseCategoricalCrossentropy(from_logits=True),
+... metrics=tf.metrics.SparseCategoricalAccuracy(),
+... )
+
+>>> model.fit(tf_train_dataset, validation_data=tf_validation_dataset, epochs=3)
+```
+
+
+
+
+
+
+
+Ottieni l'accesso gratuito a una GPU sul cloud se non ne possiedi una usando un notebook sul web come [Colaboratory](https://colab.research.google.com/) o [SageMaker StudioLab](https://studiolab.sagemaker.aws/).
+
+
+
+Ottimo, adesso possiamo addestrare! 🥳
+
+### Training loop
+
+Per tenere traccia dei tuoi progressi durante l'addestramento, usa la libreria [tqdm](https://tqdm.github.io/) per aggiungere una progress bar sopra il numero dei passi di addestramento:
+
+```py
+>>> from tqdm.auto import tqdm
+
+>>> progress_bar = tqdm(range(num_training_steps))
+
+>>> model.train()
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... outputs = model(**batch)
+... loss = outputs.loss
+... loss.backward()
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+### Metriche
+
+Proprio come è necessario aggiungere una funzione di valutazione del [`Trainer`], è necessario fare lo stesso quando si scrive il proprio ciclo di addestramento. Ma invece di calcolare e riportare la metrica alla fine di ogni epoca, questa volta accumulerai tutti i batch con [`add_batch`](https://huggingface.co/docs/datasets/package_reference/main_classes?highlight=add_batch#datasets.Metric.add_batch) e calcolerai la metrica alla fine.
+
+```py
+>>> metric = load_metric("accuracy")
+>>> model.eval()
+>>> for batch in eval_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... with torch.no_grad():
+... outputs = model(**batch)
+
+... logits = outputs.logits
+... predictions = torch.argmax(logits, dim=-1)
+... metric.add_batch(predictions=predictions, references=batch["labels"])
+
+>>> metric.compute()
+```
+
+
+
+
+
+Windowsを使用している場合、`RUN_SLOW=1`を`SET RUN_SLOW=1`に置き換えてください。
+
+
+
+次に、*brand_new_bert*に特有のすべての特徴は、別個のテスト内で追加されるべきです。
+`BrandNewBertModelTester`/`BrandNewBertModelTest`の下に。この部分はよく忘れられますが、2つの点で非常に役立ちます:
+
+- モデルの追加中に獲得した知識をコミュニティに伝え、*brand_new_bert*の特別な機能がどのように動作するかを示すことによって、知識の共有を支援します。
+- 将来の貢献者は、これらの特別なテストを実行することでモデルへの変更を迅速にテストできます。
+
+**9. トークナイザの実装**
+
+次に、*brand_new_bert*のトークナイザを追加する必要があります。通常、トークナイザは🤗 Transformersの既存のトークナイザと同等か非常に似ています。
+
+トークナイザが正しく動作することを確認するためには、まず、元のリポジトリ内で文字列を入力し、`input_ids`を返すスクリプトを作成することをお勧めします。
+このスクリプトは、次のように見えるかもしれません(疑似コードで示します):
+
+```python
+input_str = "This is a long example input string containing special characters .$?-, numbers 2872 234 12 and words."
+model = BrandNewBertModel.load_pretrained_checkpoint("/path/to/checkpoint/")
+input_ids = model.tokenize(input_str)
+```
+
+オリジナルのリポジトリを詳しく調査し、正しいトークナイザの関数を見つける必要があるかもしれません。
+または、オリジナルのリポジトリのクローンを変更して、`input_ids`だけを出力するようにする必要があるかもしれません。
+オリジナルのリポジトリを使用した機能的なトークナイゼーションスクリプトを作成した後、
+🤗 Transformers向けの類似したスクリプトを作成する必要があります。
+以下のように見えるべきです:
+
+```python
+from transformers import BrandNewBertTokenizer
+
+input_str = "This is a long example input string containing special characters .$?-, numbers 2872 234 12 and words."
+
+tokenizer = BrandNewBertTokenizer.from_pretrained("/path/to/tokenizer/folder/")
+
+input_ids = tokenizer(input_str).input_ids
+```
+
+`input_ids`が同じ値を生成した場合、最終ステップとしてトークナイザのテストファイルも追加するべきです。
+
+*brand_new_bert*のモデルングテストファイルと同様に、*brand_new_bert*のトークナイズテストファイルには、いくつかのハードコードされた統合テストが含まれるべきです。
+
+**10. エンドツーエンド統合テストの実行**
+
+トークナイザを追加した後、`🤗 Transformers`内の`tests/models/brand_new_bert/test_modeling_brand_new_bert.py`に
+モデルとトークナイザの両方を使用するいくつかのエンドツーエンド統合テストも追加する必要があります。
+このようなテストは、🤗 Transformersの実装が期待どおりに機能することを示すべきです。
+意味のあるテキスト対テキストのサンプルが含まれます。有用なテキスト対テキストのサンプルには、ソースからターゲットへの翻訳ペア、記事から要約へのペア、質問から回答へのペアなどが含まれます。
+ポートされたチェックポイントがダウンストリームタスクでファインチューニングされていない場合、モデルのテストに依存するだけで十分です。
+モデルが完全に機能していることを確認するために、すべてのテストをGPU上で実行することもお勧めします。
+モデルの内部テンソルに`.to(self.device)`ステートメントを追加するのを忘れる可能性があるため、そのようなテストではエラーが表示されることがあります。
+GPUにアクセスできない場合、Hugging Faceチームが代わりにこれらのテストを実行できます。
+
+**11. ドキュメントの追加**
+
+これで、*brand_new_bert*の必要なすべての機能が追加されました - ほぼ完了です!残りの追加すべきことは、良いドキュメントとドキュメントページです。
+Cookiecutterが`docs/source/model_doc/brand_new_bert.md`というテンプレートファイルを追加しているはずで、これを記入する必要があります。
+モデルのユーザーは通常、モデルを使用する前にまずこのページを見ます。したがって、ドキュメンテーションは理解しやすく簡潔である必要があります。
+モデルの使用方法を示すためにいくつかの*Tips*を追加することはコミュニティにとって非常に役立ちます。ドキュメンテーションに関しては、Hugging Faceチームに問い合わせることをためらわないでください。
+
+次に、`src/transformers/models/brand_new_bert/modeling_brand_new_bert.py`に追加されたドキュメンテーション文字列が正しいこと、およびすべての必要な入力および出力を含んでいることを確認してください。
+ドキュメンテーションの書き方とドキュメンテーション文字列のフォーマットについて詳細なガイドが[こちら](writing-documentation)にあります。
+ドキュメンテーションは通常、コミュニティとモデルの最初の接触点であるため、コードと同じくらい注意深く扱うべきであることを常に念頭に置いてください。
+
+**コードのリファクタリング**
+
+素晴らしい、これで*brand_new_bert*に必要なすべてのコードが追加されました。
+この時点で、次のようなポテンシャルなコードスタイルの誤りを訂正するために以下を実行する必要があります:
+
+```bash
+make style
+```
+
+あなたのコーディングスタイルが品質チェックをパスすることを確認してください:
+
+```bash
+make quality
+```
+
+🤗 Transformersの非常に厳格なデザインテストには、まだ合格していない可能性があるいくつかの他のテストが存在するかもしれません。
+これは、ドキュメント文字列に情報が不足しているか、名前が間違っていることが原因であることが多いです。Hugging Faceチームは、ここで詰まっている場合には必ず助けてくれるでしょう。
+
+最後に、コードが正しく機能することを確認した後、コードをリファクタリングするのは常に良いアイデアです。
+すべてのテストがパスした今、追加したコードを再度確認してリファクタリングを行うのは良いタイミングです。
+
+これでコーディングの部分は完了しました、おめでとうございます! 🎉 あなたは素晴らしいです! 😎
+
+**12. モデルをモデルハブにアップロード**
+
+最後のパートでは、すべてのチェックポイントをモデルハブに変換してアップロードし、各アップロードしたモデルチェックポイントにモデルカードを追加する必要があります。
+モデルハブの機能について詳しくは、[Model sharing and uploading Page](model_sharing)を読んで理解できます。
+ここでは、*brand_new_bert*の著者組織の下にモデルをアップロードできるように必要なアクセス権を取得するために、Hugging Faceチームと協力する必要があります。
+`transformers`のすべてのモデルに存在する`push_to_hub`メソッドは、チェックポイントをハブにプッシュする迅速かつ効率的な方法です。
+以下に、少しのコードスニペットを示します:
+
+```python
+brand_new_bert.push_to_hub("brand_new_bert")
+# Uncomment the following line to push to an organization.
+# brand_new_bert.push_to_hub("/brand_new_bert")
+```
+
+各チェックポイントに適切なモデルカードを作成する価値があります。モデルカードは、この特定のチェックポイントの特性をハイライトするべきです。例えば、このチェックポイントはどのデータセットで事前学習/ファインチューニングされたか、どのような下流タスクでモデルを使用すべきかを示すべきです。また、モデルの正しい使用方法に関するコードも含めるべきです。
+
+**13.(オプション)ノートブックの追加**
+
+*brand_new_bert*を推論または下流タスクのファインチューニングにどのように詳細に使用できるかを示すノートブックを追加することは非常に役立ちます。これはあなたのPRをマージするために必須ではありませんが、コミュニティにとって非常に有用です。
+
+**14. 完成したPRの提出**
+
+プログラミングが完了したら、最後のステップに移動し、PRをメインブランチにマージしましょう。通常、Hugging Faceチームはこの時点で既にあなたをサポートしているはずですが、PRに良い説明を追加し、コードにコメントを追加して、レビュアーに特定の設計の選択肢を指摘したい場合はコメントを追加することも価値があります。
+
+### Share your work!!
+
+さあ、コミュニティからあなたの作業に対する評価を得る時が来ました!モデルの追加を完了することは、TransformersおよびNLPコミュニティにとって重要な貢献です。あなたのコードとポートされた事前学習済みモデルは、何百人、何千人という開発者や研究者によって確実に使用されるでしょう。あなたの仕事に誇りを持ち、コミュニティとあなたの成果を共有しましょう。
+
+**あなたはコミュニティの誰でも簡単にアクセスできる別のモデルを作成しました! 🤯**
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/attention.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/attention.md
new file mode 100644
index 0000000000000000000000000000000000000000..4c452ffa42229936883510abd652bd5e5ab0f4e8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/attention.md
@@ -0,0 +1,52 @@
+
+
+# Attention mechanism
+
+ほとんどのTransformerモデルは、アテンション行列が正方形であるという意味で完全なアテンションを使用します。
+これは、長いテキストを扱う場合に計算のボトルネックとなることがあります。LongformerやReformerは、より効率的でトレーニングを高速化するためにアテンション行列のスパースバージョンを使用しようとするモデルです。
+
+## LSH attention
+
+[Reformer](model_doc/reformer)はLSH(局所的に散在ハッシュ)アテンションを使用します。
+ソフトマックス(QK^t)では、行列QK^tの中で(ソフトマックス次元で)最も大きな要素のみが有用な寄与を提供します。
+したがって、各クエリqについて、クエリqに近いキーkのみを考慮できます。
+qとkが近いかどうかを決定するために、ハッシュ関数が使用されます。
+アテンションマスクは変更され、現在のトークンをマスク化します(最初の位置を除く)。
+なぜなら、それはクエリとキーが等しい(つまり非常に似ている)クエリとキーを提供するからです。
+ハッシュは多少ランダムかもしれないため、実際にはいくつかのハッシュ関数が使用され(n_roundsパラメータで決定されます)、それらが平均化されます。
+
+## Local attention
+
+[Longformer](model_doc/longformer)はローカルアテンションを使用します。
+しばしば、ローカルコンテキスト(例:左右の2つのトークンは何ですか?)は、特定のトークンに対して行動を起こすのに十分です。
+また、小さなウィンドウを持つアテンションレイヤーを積み重ねることで、最後のレイヤーはウィンドウ内のトークンだけでなく、ウィンドウ内のトークンを超えて受容野を持つようになり、文全体の表現を構築できます。
+
+一部の事前選択された入力トークンにはグローバルアテンションも与えられます。
+これらの少数のトークンに対して、アテンション行列はすべてのトークンにアクセスでき、このプロセスは対称的です。
+他のすべてのトークンは、これらの特定のトークンにアクセスできます(ローカルウィンドウ内のトークンに加えて)。
+これは、論文の図2dに示されており、以下はサンプルのアテンションマスクです:
+
+
+
+
+
+アーキテクチャはモデルの骨格を指し、チェックポイントは特定のアーキテクチャの重みです。
+たとえば、[BERT](https://huggingface.co/google-bert/bert-base-uncased)はアーキテクチャであり、`google-bert/bert-base-uncased`はチェックポイントです。
+モデルはアーキテクチャまたはチェックポイントのどちらを指す一般的な用語です。
+
+
+
+このチュートリアルでは、以下を学習します:
+
+* 事前学習済みトークナイザをロードする。
+* 事前学習済み画像プロセッサをロードする。
+* 事前学習済み特徴量抽出器をロードする。
+* 事前学習済みプロセッサをロードする。
+* 事前学習済みモデルをロードする。
+
+## AutoTokenizer
+
+ほとんどのNLPタスクはトークナイザで始まります。トークナイザは入力をモデルで処理できる形式に変換します。
+
+[`AutoTokenizer.from_pretrained`]を使用してトークナイザをロードします:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+```
+
+
+次に、以下のように入力をトークナイズします:
+
+```py
+>>> sequence = "In a hole in the ground there lived a hobbit."
+>>> print(tokenizer(sequence))
+{'input_ids': [101, 1999, 1037, 4920, 1999, 1996, 2598, 2045, 2973, 1037, 7570, 10322, 4183, 1012, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+## AutoImageProcessor
+
+ビジョンタスクの場合、画像プロセッサが画像を正しい入力形式に変換します。
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+```
+
+## AutoFeatureExtractor
+
+オーディオタスクの場合、特徴量抽出器がオーディオ信号を正しい入力形式に変換します。
+
+[`AutoFeatureExtractor.from_pretrained`]を使用して特徴量抽出器をロードします.
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained(
+... "ehcalabres/wav2vec2-lg-xlsr-en-speech-emotion-recognition"
+... )
+```
+
+## AutoProcessor
+
+マルチモーダルタスクの場合、2つの前処理ツールを組み合わせるプロセッサが必要です。たとえば、
+[LayoutLMV2](model_doc/layoutlmv2)モデルは画像を処理するための画像プロセッサとテキストを処理するためのトークナイザが必要です。
+プロセッサはこれらの両方を組み合わせます。
+
+[`AutoProcessor.from_pretrained`]を使用してプロセッサをロードします:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("microsoft/layoutlmv2-base-uncased")
+```
+
+## AutoModel
+
+
+
+最後に、`AutoModelFor`クラスは特定のタスクに対して事前学習済みモデルをロードできます(使用可能なタスクの完全な一覧については[こちら](model_doc/auto)を参照)。
+たとえば、[`AutoModelForSequenceClassification.from_pretrained`]を使用してシーケンス分類用のモデルをロードできます:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+同じチェックポイントを再利用して異なるタスクのアーキテクチャをロードできます:
+
+```py
+>>> from transformers import AutoModelForTokenClassification
+
+>>> model = AutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+PyTorchモデルの場合、 `from_pretrained()`メソッドは内部で`torch.load()`を使用し、内部的には`pickle`を使用しており、セキュリティの問題が知られています。
+一般的には、信頼性のないソースから取得した可能性があるモデルや改ざんされた可能性のあるモデルをロードしないでください。
+このセキュリティリスクは、`Hugging Face Hub`でホストされている公開モデルに対して部分的に緩和されており、各コミットでマルウェアのスキャンが行われています。
+GPGを使用した署名済みコミットの検証などのベストプラクティスについては、Hubのドキュメンテーションを参照してください。
+
+TensorFlowおよびFlaxのチェックポイントには影響がなく、`from_pretrained`メソッドの`from_tf`および`from_flax`引数を使用してPyTorchアーキテクチャ内でロードできます。
+
+
+
+一般的に、事前学習済みモデルのインスタンスをロードするために`AutoTokenizer`クラスと`AutoModelFor`クラスの使用をお勧めします。
+これにより、常に正しいアーキテクチャをロードできます。
+次の[tutorial](preprocessing)では、新しくロードしたトークナイザ、画像プロセッサ、特徴量抽出器、およびプロセッサを使用して、ファインチューニング用にデータセットを前処理する方法を学びます。
+
+
+最後に、`TFAutoModelFor`クラスは特定のタスクに対して事前学習済みモデルをロードできます(使用可能なタスクの完全な一覧についてはこちらを参照)。
+たとえば、[`TFAutoModelForSequenceClassification.from_pretrained`]を使用してシーケンス分類用のモデルをロードできます:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+同じチェックポイントを再利用して異なるタスクのアーキテクチャをロードできます:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+一般的には、事前学習済みモデルのインスタンスをロードするために`AutoTokenizer`クラスと`TFAutoModelFor`クラスの使用をお勧めします。
+これにより、常に正しいアーキテクチャをロードできます。
+次の[tutorial](preproccesing)では、新しくロードしたトークナイザ、画像プロセッサ、特徴量抽出器、およびプロセッサを使用して、ファインチューニング用にデータセットを前処理する方法を学びます。
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/benchmarks.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/benchmarks.md
new file mode 100644
index 0000000000000000000000000000000000000000..7312aae8ce5b7cade6efae449b0ede5cb13779e0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/benchmarks.md
@@ -0,0 +1,381 @@
+
+
+# Benchmarks
+
+
+
+Hugging Faceのベンチマークツールは非推奨であり、Transformerモデルの速度とメモリの複雑さを測定するために外部のベンチマークライブラリを使用することをお勧めします。
+
+
+
+[[open-in-colab]]
+
+🤗 Transformersモデルをベンチマークし、ベストプラクティス、すでに利用可能なベンチマークについて見てみましょう。
+
+🤗 Transformersモデルをベンチマークする方法について詳しく説明したノートブックは[こちら](https://github.com/huggingface/notebooks/tree/main/examples/benchmark.ipynb)で利用できます。
+
+## How to benchmark 🤗 Transformers models
+
+[`PyTorchBenchmark`]クラスと[`TensorFlowBenchmark`]クラスを使用すると、🤗 Transformersモデルを柔軟にベンチマークできます。
+ベンチマーククラスを使用すると、_ピークメモリ使用量_ および _必要な時間_ を _推論_ および _トレーニング_ の両方について測定できます。
+
+
+
+ここでの _推論_ は、単一のフォワードパスによって定義され、 _トレーニング_ は単一のフォワードパスと
+バックワードパスによって定義されます。
+
+
+
+ベンチマーククラス[`PyTorchBenchmark`]と[`TensorFlowBenchmark`]は、それぞれのベンチマーククラスに対する適切な設定を含む [`PyTorchBenchmarkArguments`] および [`TensorFlowBenchmarkArguments`] タイプのオブジェクトを必要とします。
+[`PyTorchBenchmarkArguments`] および [`TensorFlowBenchmarkArguments`] はデータクラスであり、それぞれのベンチマーククラスに対するすべての関連する設定を含んでいます。
+次の例では、タイプ _bert-base-cased_ のBERTモデルをベンチマークする方法が示されています。
+
+
+
+```py
+>>> from transformers import PyTorchBenchmark, PyTorchBenchmarkArguments
+
+>>> args = PyTorchBenchmarkArguments(models=["google-bert/bert-base-uncased"], batch_sizes=[8], sequence_lengths=[8, 32, 128, 512])
+>>> benchmark = PyTorchBenchmark(args)
+```
+
+
+```py
+>>> from transformers import TensorFlowBenchmark, TensorFlowBenchmarkArguments
+
+>>> args = TensorFlowBenchmarkArguments(
+... models=["google-bert/bert-base-uncased"], batch_sizes=[8], sequence_lengths=[8, 32, 128, 512]
+... )
+>>> benchmark = TensorFlowBenchmark(args)
+```
+
+
+
+
+ここでは、ベンチマーク引数のデータクラスに対して、`models`、`batch_sizes`
+および`sequence_lengths`の3つの引数が指定されています。引数`models`は必須で、
+[モデルハブ](https://huggingface.co/models)からのモデル識別子の`リスト`を期待し
+ます。`batch_sizes`と`sequence_lengths`の2つの`リスト`引数は
+モデルのベンチマーク対象となる`input_ids`のサイズを定義します。
+ベンチマーク引数データクラスを介して設定できる他の多くのパラメータがあります。これらの詳細については、直接ファイル
+`src/transformers/benchmark/benchmark_args_utils.py`、
+`src/transformers/benchmark/benchmark_args.py`(PyTorch用)、および`src/transformers/benchmark/benchmark_args_tf.py`(Tensorflow用)
+を参照するか、次のシェルコマンドをルートから実行すると、PyTorchとTensorflowのそれぞれに対して設定可能なすべてのパラメータの記述的なリストが表示されます。
+
+
+
+```bash
+python examples/pytorch/benchmarking/run_benchmark.py --help
+```
+
+インスタンス化されたベンチマークオブジェクトは、単に `benchmark.run()` を呼び出すことで実行できます。
+
+
+```py
+>>> results = benchmark.run()
+>>> print(results)
+==================== INFERENCE - SPEED - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Time in s
+--------------------------------------------------------------------------------
+google-bert/bert-base-uncased 8 8 0.006
+google-bert/bert-base-uncased 8 32 0.006
+google-bert/bert-base-uncased 8 128 0.018
+google-bert/bert-base-uncased 8 512 0.088
+--------------------------------------------------------------------------------
+
+==================== INFERENCE - MEMORY - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Memory in MB
+--------------------------------------------------------------------------------
+google-bert/bert-base-uncased 8 8 1227
+google-bert/bert-base-uncased 8 32 1281
+google-bert/bert-base-uncased 8 128 1307
+google-bert/bert-base-uncased 8 512 1539
+--------------------------------------------------------------------------------
+
+==================== ENVIRONMENT INFORMATION ====================
+
+- transformers_version: 2.11.0
+- framework: PyTorch
+- use_torchscript: False
+- framework_version: 1.4.0
+- python_version: 3.6.10
+- system: Linux
+- cpu: x86_64
+- architecture: 64bit
+- date: 2020-06-29
+- time: 08:58:43.371351
+- fp16: False
+- use_multiprocessing: True
+- only_pretrain_model: False
+- cpu_ram_mb: 32088
+- use_gpu: True
+- num_gpus: 1
+- gpu: TITAN RTX
+- gpu_ram_mb: 24217
+- gpu_power_watts: 280.0
+- gpu_performance_state: 2
+- use_tpu: False
+```
+
+
+```bash
+python examples/tensorflow/benchmarking/run_benchmark_tf.py --help
+```
+
+インスタンス化されたベンチマークオブジェクトは、単に `benchmark.run()` を呼び出すことで実行できます。
+
+
+
+```py
+>>> results = benchmark.run()
+>>> print(results)
+>>> results = benchmark.run()
+>>> print(results)
+==================== INFERENCE - SPEED - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Time in s
+--------------------------------------------------------------------------------
+google-bert/bert-base-uncased 8 8 0.005
+google-bert/bert-base-uncased 8 32 0.008
+google-bert/bert-base-uncased 8 128 0.022
+google-bert/bert-base-uncased 8 512 0.105
+--------------------------------------------------------------------------------
+
+==================== INFERENCE - MEMORY - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Memory in MB
+--------------------------------------------------------------------------------
+google-bert/bert-base-uncased 8 8 1330
+google-bert/bert-base-uncased 8 32 1330
+google-bert/bert-base-uncased 8 128 1330
+google-bert/bert-base-uncased 8 512 1770
+--------------------------------------------------------------------------------
+
+==================== ENVIRONMENT INFORMATION ====================
+
+- transformers_version: 2.11.0
+- framework: Tensorflow
+- use_xla: False
+- framework_version: 2.2.0
+- python_version: 3.6.10
+- system: Linux
+- cpu: x86_64
+- architecture: 64bit
+- date: 2020-06-29
+- time: 09:26:35.617317
+- fp16: False
+- use_multiprocessing: True
+- only_pretrain_model: False
+- cpu_ram_mb: 32088
+- use_gpu: True
+- num_gpus: 1
+- gpu: TITAN RTX
+- gpu_ram_mb: 24217
+- gpu_power_watts: 280.0
+- gpu_performance_state: 2
+- use_tpu: False
+```
+
+
+
+デフォルトでは、_推論時間_ と _必要なメモリ_ がベンチマークされます。
+上記の例の出力では、最初の2つのセクションが _推論時間_ と _推論メモリ_
+に対応する結果を示しています。さらに、計算環境に関するすべての関連情報、
+例えば GPU タイプ、システム、ライブラリのバージョンなどが、_ENVIRONMENT INFORMATION_ の下に表示されます。この情報は、[`PyTorchBenchmarkArguments`]
+および [`TensorFlowBenchmarkArguments`] に引数 `save_to_csv=True`
+を追加することで、オプションで _.csv_ ファイルに保存することができます。この場合、各セクションは別々の _.csv_ ファイルに保存されます。_.csv_
+ファイルへのパスは、データクラスの引数を使用してオプションで定義できます。
+
+モデル識別子、例えば `google-bert/bert-base-uncased` を使用して事前学習済みモデルをベンチマークする代わりに、利用可能な任意のモデルクラスの任意の設定をベンチマークすることもできます。この場合、ベンチマーク引数と共に設定の `list` を挿入する必要があります。
+
+
+
+
+```py
+>>> from transformers import PyTorchBenchmark, PyTorchBenchmarkArguments, BertConfig
+
+>>> args = PyTorchBenchmarkArguments(
+... models=["bert-base", "bert-384-hid", "bert-6-lay"], batch_sizes=[8], sequence_lengths=[8, 32, 128, 512]
+... )
+>>> config_base = BertConfig()
+>>> config_384_hid = BertConfig(hidden_size=384)
+>>> config_6_lay = BertConfig(num_hidden_layers=6)
+
+>>> benchmark = PyTorchBenchmark(args, configs=[config_base, config_384_hid, config_6_lay])
+>>> benchmark.run()
+==================== INFERENCE - SPEED - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Time in s
+--------------------------------------------------------------------------------
+bert-base 8 128 0.006
+bert-base 8 512 0.006
+bert-base 8 128 0.018
+bert-base 8 512 0.088
+bert-384-hid 8 8 0.006
+bert-384-hid 8 32 0.006
+bert-384-hid 8 128 0.011
+bert-384-hid 8 512 0.054
+bert-6-lay 8 8 0.003
+bert-6-lay 8 32 0.004
+bert-6-lay 8 128 0.009
+bert-6-lay 8 512 0.044
+--------------------------------------------------------------------------------
+
+==================== INFERENCE - MEMORY - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Memory in MB
+--------------------------------------------------------------------------------
+bert-base 8 8 1277
+bert-base 8 32 1281
+bert-base 8 128 1307
+bert-base 8 512 1539
+bert-384-hid 8 8 1005
+bert-384-hid 8 32 1027
+bert-384-hid 8 128 1035
+bert-384-hid 8 512 1255
+bert-6-lay 8 8 1097
+bert-6-lay 8 32 1101
+bert-6-lay 8 128 1127
+bert-6-lay 8 512 1359
+--------------------------------------------------------------------------------
+
+==================== ENVIRONMENT INFORMATION ====================
+
+- transformers_version: 2.11.0
+- framework: PyTorch
+- use_torchscript: False
+- framework_version: 1.4.0
+- python_version: 3.6.10
+- system: Linux
+- cpu: x86_64
+- architecture: 64bit
+- date: 2020-06-29
+- time: 09:35:25.143267
+- fp16: False
+- use_multiprocessing: True
+- only_pretrain_model: False
+- cpu_ram_mb: 32088
+- use_gpu: True
+- num_gpus: 1
+- gpu: TITAN RTX
+- gpu_ram_mb: 24217
+- gpu_power_watts: 280.0
+- gpu_performance_state: 2
+- use_tpu: False
+```
+
+
+```py
+>>> from transformers import TensorFlowBenchmark, TensorFlowBenchmarkArguments, BertConfig
+
+>>> args = TensorFlowBenchmarkArguments(
+... models=["bert-base", "bert-384-hid", "bert-6-lay"], batch_sizes=[8], sequence_lengths=[8, 32, 128, 512]
+... )
+>>> config_base = BertConfig()
+>>> config_384_hid = BertConfig(hidden_size=384)
+>>> config_6_lay = BertConfig(num_hidden_layers=6)
+
+>>> benchmark = TensorFlowBenchmark(args, configs=[config_base, config_384_hid, config_6_lay])
+>>> benchmark.run()
+==================== INFERENCE - SPEED - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Time in s
+--------------------------------------------------------------------------------
+bert-base 8 8 0.005
+bert-base 8 32 0.008
+bert-base 8 128 0.022
+bert-base 8 512 0.106
+bert-384-hid 8 8 0.005
+bert-384-hid 8 32 0.007
+bert-384-hid 8 128 0.018
+bert-384-hid 8 512 0.064
+bert-6-lay 8 8 0.002
+bert-6-lay 8 32 0.003
+bert-6-lay 8 128 0.0011
+bert-6-lay 8 512 0.074
+--------------------------------------------------------------------------------
+
+==================== INFERENCE - MEMORY - RESULT ====================
+--------------------------------------------------------------------------------
+Model Name Batch Size Seq Length Memory in MB
+--------------------------------------------------------------------------------
+bert-base 8 8 1330
+bert-base 8 32 1330
+bert-base 8 128 1330
+bert-base 8 512 1770
+bert-384-hid 8 8 1330
+bert-384-hid 8 32 1330
+bert-384-hid 8 128 1330
+bert-384-hid 8 512 1540
+bert-6-lay 8 8 1330
+bert-6-lay 8 32 1330
+bert-6-lay 8 128 1330
+bert-6-lay 8 512 1540
+--------------------------------------------------------------------------------
+
+==================== ENVIRONMENT INFORMATION ====================
+
+- transformers_version: 2.11.0
+- framework: Tensorflow
+- use_xla: False
+- framework_version: 2.2.0
+- python_version: 3.6.10
+- system: Linux
+- cpu: x86_64
+- architecture: 64bit
+- date: 2020-06-29
+- time: 09:38:15.487125
+- fp16: False
+- use_multiprocessing: True
+- only_pretrain_model: False
+- cpu_ram_mb: 32088
+- use_gpu: True
+- num_gpus: 1
+- gpu: TITAN RTX
+- gpu_ram_mb: 24217
+- gpu_power_watts: 280.0
+- gpu_performance_state: 2
+- use_tpu: False
+```
+
+
+
+カスタマイズされたBertModelクラスの構成に対する推論時間と必要なメモリのベンチマーク
+
+この機能は、モデルをトレーニングする際にどの構成を選択すべきかを決定する際に特に役立つことがあります。
+
+## Benchmark best practices
+
+このセクションでは、モデルをベンチマークする際に注意すべきいくつかのベストプラクティスをリストアップしています。
+
+- 現在、単一デバイスのベンチマークしかサポートされていません。GPUでベンチマークを実行する場合、コードを実行するデバイスをユーザーが指定することを推奨します。
+ これはシェルで`CUDA_VISIBLE_DEVICES`環境変数を設定することで行えます。例:`export CUDA_VISIBLE_DEVICES=0`を実行してからコードを実行します。
+- `no_multi_processing`オプションは、テストおよびデバッグ用にのみ`True`に設定すべきです。正確なメモリ計測を確保するために、各メモリベンチマークを別々のプロセスで実行することをお勧めします。これにより、`no_multi_processing`が`True`に設定されます。
+- モデルのベンチマーク結果を共有する際には、常に環境情報を記述するべきです。異なるGPUデバイス、ライブラリバージョンなどでベンチマーク結果が大きく異なる可能性があるため、ベンチマーク結果単体ではコミュニティにとってあまり有用ではありません。
+
+## Sharing your benchmark
+
+以前、すべての利用可能なコアモデル(当時10モデル)に対して、多くの異なる設定で推論時間のベンチマークが行われました:PyTorchを使用し、TorchScriptの有無、TensorFlowを使用し、XLAの有無などです。これらのテストはすべてCPUで行われました(TensorFlow XLAを除く)。
+
+このアプローチの詳細については、[次のブログポスト](https://medium.com/huggingface/benchmarking-transformers-pytorch-and-tensorflow-e2917fb891c2)に詳しく説明されており、結果は[こちら](https://docs.google.com/spreadsheets/d/1sryqufw2D0XlUH4sq3e9Wnxu5EAQkaohzrJbd5HdQ_w/edit?usp=sharing)で利用できます。
+
+新しいベンチマークツールを使用すると、コミュニティとベンチマーク結果を共有することがこれまで以上に簡単になります。
+
+- [PyTorchベンチマーク結果](https://github.com/huggingface/transformers/tree/main/examples/pytorch/benchmarking/README.md)。
+- [TensorFlowベンチマーク結果](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/benchmarking/README.md)。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/bertology.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/bertology.md
new file mode 100644
index 0000000000000000000000000000000000000000..167ed007bbe4374d0983c95e3e9a104725bef947
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/bertology.md
@@ -0,0 +1,34 @@
+
+
+
+# BERTology
+
+大規模なトランスフォーマー、例えばBERTの内部動作を調査する研究領域が急成長しています(これを「BERTology」とも呼びます)。この分野の良い例は以下です:
+
+- BERT Rediscovers the Classical NLP Pipeline by Ian Tenney, Dipanjan Das, Ellie Pavlick:
+ [論文リンク](https://arxiv.org/abs/1905.05950)
+- Are Sixteen Heads Really Better than One? by Paul Michel, Omer Levy, Graham Neubig: [論文リンク](https://arxiv.org/abs/1905.10650)
+- What Does BERT Look At? An Analysis of BERT's Attention by Kevin Clark, Urvashi Khandelwal, Omer Levy, Christopher D. Manning: [論文リンク](https://arxiv.org/abs/1906.04341)
+- CAT-probing: A Metric-based Approach to Interpret How Pre-trained Models for Programming Language Attend Code Structure: [論文リンク](https://arxiv.org/abs/2210.04633)
+
+この新しい分野の発展を支援するために、BERT/GPT/GPT-2モデルにいくつかの追加機能を組み込み、人々が内部表現にアクセスできるようにしました。これらの機能は、主にPaul Michel氏の優れた研究([論文リンク](https://arxiv.org/abs/1905.10650))に基づいています。具体的には、以下の機能が含まれています:
+
+- BERT/GPT/GPT-2のすべての隠れ状態にアクセスすることができます。
+- BERT/GPT/GPT-2の各ヘッドの注意重みにアクセスできます。
+- ヘッドの出力値と勾配を取得し、ヘッドの重要性スコアを計算し、[論文リンク](https://arxiv.org/abs/1905.10650)で説明されているようにヘッドを削減できます。
+
+これらの機能を理解し、使用するのを支援するために、特定のサンプルスクリプト「[bertology.py](https://github.com/huggingface/transformers/tree/main/examples/research_projects/bertology/run_bertology.py)」を追加しました。このスクリプトは、GLUEで事前トレーニングされたモデルから情報を抽出し、ヘッドを削減する役割を果たします。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/big_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/big_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..78852dc4374cceafdded1d91a69a0ae04e3d90ea
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/big_models.md
@@ -0,0 +1,130 @@
+
+
+# Instantiating a big model
+
+非常に大規模な事前学習済みモデルを使用する場合、RAMの使用量を最小限に抑えることは課題の1つです。通常のPyTorchのワークフローは次のとおりです:
+
+1. ランダムな重みを持つモデルを作成します。
+2. 事前学習済みの重みをロードします。
+3. これらの事前学習済みの重みをランダムなモデルに配置します。
+
+ステップ1と2の両方がメモリにモデルの完全なバージョンを必要とし、ほとんどの場合は問題ありませんが、モデルのサイズが数ギガバイトになると、これらの2つのコピーをRAMから排除することができなくなる可能性があります。さらに悪いことに、分散トレーニングを実行するために`torch.distributed`を使用している場合、各プロセスは事前学習済みモデルをロードし、これらの2つのコピーをRAMに保存します。
+
+
+
+ランダムに作成されたモデルは、メモリ内に「空の」テンソルで初期化されます。これらのランダムな値は、メモリの特定のチャンクにあったものを使用します(したがって、ランダムな値はその時点でのメモリチャンク内の値です)。モデル/パラメータの種類に適した分布(たとえば、正規分布)に従うランダムな初期化は、ステップ3で初期化されていない重みに対して、できるだけ高速に実行されます!
+
+
+
+このガイドでは、Transformersがこの問題に対処するために提供するソリューションを探ります。なお、これは現在も開発が進行中の分野であり、将来、ここで説明されているAPIがわずかに変更される可能性があることに注意してください。
+
+## Sharded checkpoints
+
+バージョン4.18.0から、10GBを超えるサイズのモデルチェックポイントは自動的に複数の小さな部分に分割されます。`model.save_pretrained(save_dir)`を実行する際に1つの単一のチェックポイントを持つ代わりに、いくつかの部分的なチェックポイント(それぞれのサイズが<10GB)と、パラメータ名をそれらが格納されているファイルにマップするインデックスが生成されます。
+
+`max_shard_size`パラメータでシャーディング前の最大サイズを制御できるため、例として通常サイズのモデルと小さなシャードサイズを使用します。従来のBERTモデルを使用してみましょう。
+
+
+```py
+from transformers import AutoModel
+
+model = AutoModel.from_pretrained("google-bert/bert-base-cased")
+```
+
+もし[`~PreTrainedModel.save_pretrained`]を使用して保存する場合、新しいフォルダが2つのファイルを含む形で作成されます: モデルの設定情報とその重み情報です。
+
+```py
+>>> import os
+>>> import tempfile
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir)
+... print(sorted(os.listdir(tmp_dir)))
+['config.json', 'pytorch_model.bin']
+```
+
+最大シャードサイズを200MBに設定します:
+
+```py
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... print(sorted(os.listdir(tmp_dir)))
+['config.json', 'pytorch_model-00001-of-00003.bin', 'pytorch_model-00002-of-00003.bin', 'pytorch_model-00003-of-00003.bin', 'pytorch_model.bin.index.json']
+```
+
+モデルの設定の上に、3つの異なる重みファイルと、`index.json`ファイルが見られます。これは私たちのインデックスです。
+このようなチェックポイントは、[`~PreTrainedModel.from_pretrained`]メソッドを使用して完全に再ロードできます:
+
+```py
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... new_model = AutoModel.from_pretrained(tmp_dir)
+```
+
+主要な利点は、大規模なモデルの場合、上記のワークフローのステップ2において、各チェックポイントのシャードが前のシャードの後にロードされ、RAMのメモリ使用量をモデルのサイズと最大のシャードのサイズを合わせたものに制限できることです。
+
+内部では、インデックスファイルが使用され、どのキーがチェックポイントに存在し、対応する重みがどこに格納されているかを判断します。このインデックスは通常のJSONファイルのように読み込むことができ、辞書として取得できます。
+
+
+```py
+>>> import json
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... with open(os.path.join(tmp_dir, "pytorch_model.bin.index.json"), "r") as f:
+... index = json.load(f)
+
+>>> print(index.keys())
+dict_keys(['metadata', 'weight_map'])
+```
+
+メタデータには現時点ではモデルの総サイズのみが含まれています。
+将来的には他の情報を追加する予定です:
+
+```py
+>>> index["metadata"]
+{'total_size': 433245184}
+```
+
+重みマップはこのインデックスの主要な部分であり、各パラメータ名(通常はPyTorchモデルの`state_dict`で見つかるもの)をその格納されているファイルにマップします:
+
+```py
+>>> index["weight_map"]
+{'embeddings.LayerNorm.bias': 'pytorch_model-00001-of-00003.bin',
+ 'embeddings.LayerNorm.weight': 'pytorch_model-00001-of-00003.bin',
+ ...
+```
+
+直接モデル内で[`~PreTrainedModel.from_pretrained`]を使用せずに、
+シャーディングされたチェックポイントをロードしたい場合(フルチェックポイントの場合に`model.load_state_dict()`を使用するように行う方法)、[`~modeling_utils.load_sharded_checkpoint`]を使用する必要があります:
+
+
+```py
+>>> from transformers.modeling_utils import load_sharded_checkpoint
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... load_sharded_checkpoint(model, tmp_dir)
+```
+
+
+## Low memory loading
+
+シャードされたチェックポイントは、上記のワークフローのステップ2におけるメモリ使用量を削減しますが、
+低メモリの環境でそのモデルを使用するために、Accelerateライブラリに基づいた当社のツールを活用することをお勧めします。
+
+詳細については、以下のガイドをご覧ください:[Accelerateを使用した大規模モデルの読み込み](./main_classes/model#large-model-loading)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/chat_templating.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/chat_templating.md
new file mode 100644
index 0000000000000000000000000000000000000000..ebe0a68fd42cca8aedf5c0166c88e7fa49e0069e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/chat_templating.md
@@ -0,0 +1,249 @@
+
+
+# Chat Templates
+
+## Introduction
+
+LLM(Language Model)のますます一般的な使用事例の1つは「チャット」です。
+チャットのコンテキストでは、通常の言語モデルのように単一のテキストストリングを継続するのではなく、モデルは1つ以上の「メッセージ」からなる会話を継続します。
+各メッセージには「ロール」とメッセージテキストが含まれます。
+
+最も一般的に、これらのロールはユーザーからのメッセージには「ユーザー」、モデルからのメッセージには「アシスタント」が割り当てられます。
+一部のモデルは「システム」ロールもサポートしています。
+システムメッセージは通常会話の開始時に送信され、モデルの動作方法に関する指示が含まれます。
+
+すべての言語モデル、チャット用に微調整されたモデルを含むすべてのモデルは、トークンのリニアシーケンスで動作し、ロールに特有の特別な処理を持ちません。
+つまり、ロール情報は通常、メッセージ間に制御トークンを追加して注入され、メッセージの境界と関連するロールを示すことで提供されます。
+
+残念ながら、トークンの使用方法については(まだ!)標準が存在せず、異なるモデルはチャット用のフォーマットや制御トークンが大きく異なる形式でトレーニングされています。
+これはユーザーにとって実際の問題になる可能性があります。正しいフォーマットを使用しないと、モデルは入力に混乱し、パフォーマンスが本来よりも遥かに低下します。
+これが「チャットテンプレート」が解決しようとする問題です。
+
+チャット会話は通常、各辞書が「ロール」と「コンテンツ」のキーを含み、単一のチャットメッセージを表すリストとして表現されます。
+チャットテンプレートは、指定されたモデルの会話を単一のトークン化可能なシーケンスにどのようにフォーマットするかを指定するJinjaテンプレートを含む文字列です。
+トークナイザとこの情報を保存することにより、モデルが期待する形式の入力データを取得できるようになります。
+
+さっそく、`BlenderBot` モデルを使用した例を示して具体的にしましょう。`BlenderBot` のデフォルトテンプレートは非常にシンプルで、ほとんどが対話のラウンド間に空白を追加するだけです。
+
+
+```python
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/blenderbot-400M-distill")
+
+>>> chat = [
+... {"role": "user", "content": "Hello, how are you?"},
+... {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+... {"role": "user", "content": "I'd like to show off how chat templating works!"},
+... ]
+
+>>> tokenizer.apply_chat_template(chat, tokenize=False)
+" Hello, how are you? I'm doing great. How can I help you today? I'd like to show off how chat templating works!"
+```
+
+指定された通り、チャット全体が単一の文字列にまとめられています。デフォルトの設定である「tokenize=True」を使用すると、
+その文字列もトークン化されます。しかし、より複雑なテンプレートが実際にどのように機能するかを確認するために、
+「meta-llama/Llama-2-7b-chat-hf」モデルを使用してみましょう。ただし、このモデルはゲート付きアクセスを持っており、
+このコードを実行する場合は[リポジトリでアクセスをリクエスト](https://huggingface.co/meta-llama/Llama-2-7b-chat-hf)する必要があります。
+
+```python
+>> from transformers import AutoTokenizer
+>> tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-2-7b-chat-hf")
+
+>> chat = [
+... {"role": "user", "content": "Hello, how are you?"},
+... {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+... {"role": "user", "content": "I'd like to show off how chat templating works!"},
+... ]
+
+>> tokenizer.use_default_system_prompt = False
+>> tokenizer.apply_chat_template(chat, tokenize=False)
+"[INST] Hello, how are you? [/INST] I'm doing great. How can I help you today? [INST] I'd like to show off how chat templating works! [/INST]"
+```
+
+今回、トークナイザは制御トークン [INST] と [/INST] を追加しました。これらはユーザーメッセージの開始と終了を示すためのものです(ただし、アシスタントメッセージには適用されません!)
+
+## How do chat templates work?
+
+モデルのチャットテンプレートは、`tokenizer.chat_template`属性に格納されています。チャットテンプレートが設定されていない場合、そのモデルクラスのデフォルトテンプレートが代わりに使用されます。`BlenderBot`のテンプレートを見てみましょう:
+
+```python
+
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/blenderbot-400M-distill")
+
+>>> tokenizer.chat_template
+"{% for message in messages %}{% if message['role'] == 'user' %}{{ ' ' }}{% endif %}{{ message['content'] }}{% if not loop.last %}{{ ' ' }}{% endif %}{% endfor %}{{ eos_token }}"
+```
+
+
+これは少し抑圧的ですね。可読性を高めるために、新しい行とインデントを追加しましょう。
+各ブロックの直前の空白と、ブロックの直後の最初の改行は、デフォルトでJinjaの `trim_blocks` および `lstrip_blocks` フラグを使用して削除します。
+これにより、インデントと改行を含むテンプレートを書いても正常に機能することができます。
+
+```
+{% for message in messages %}
+ {% if message['role'] == 'user' %}
+ {{ ' ' }}
+ {% endif %}
+ {{ message['content'] }}
+ {% if not loop.last %}
+ {{ ' ' }}
+ {% endif %}
+{% endfor %}
+{{ eos_token }}
+```
+
+これが初めて見る方へ、これは[Jinjaテンプレート](https://jinja.palletsprojects.com/en/3.1.x/templates/)です。
+Jinjaはテキストを生成するためのシンプルなコードを記述できるテンプレート言語です。多くの点で、コードと
+構文はPythonに似ています。純粋なPythonでは、このテンプレートは次のようになるでしょう:
+
+```python
+for idx, message in enumerate(messages):
+ if message['role'] == 'user':
+ print(' ')
+ print(message['content'])
+ if not idx == len(messages) - 1: # Check for the last message in the conversation
+ print(' ')
+print(eos_token)
+```
+
+実際に、このテンプレートは次の3つのことを行います:
+1. 各メッセージに対して、メッセージがユーザーメッセージである場合、それの前に空白を追加し、それ以外の場合は何も表示しません。
+2. メッセージの内容を追加します。
+3. メッセージが最後のメッセージでない場合、その後に2つのスペースを追加します。最後のメッセージの後にはEOSトークンを表示します。
+
+これは非常にシンプルなテンプレートです。制御トークンを追加しないし、モデルに対する指示を伝える一般的な方法である「システム」メッセージをサポートしていません。
+ただし、Jinjaはこれらのことを行うための多くの柔軟性を提供しています!
+LLaMAがフォーマットする方法に類似した入力をフォーマットするためのJinjaテンプレートを見てみましょう
+(実際のLLaMAテンプレートはデフォルトのシステムメッセージの処理や、一般的なシステムメッセージの処理が若干異なるため、
+実際のコードではこのテンプレートを使用しないでください!)
+
+
+```
+{% for message in messages %}
+ {% if message['role'] == 'user' %}
+ {{ bos_token + '[INST] ' + message['content'] + ' [/INST]' }}
+ {% elif message['role'] == 'system' %}
+ {{ '<>\\n' + message['content'] + '\\n< >\\n\\n' }}
+ {% elif message['role'] == 'assistant' %}
+ {{ ' ' + message['content'] + ' ' + eos_token }}
+ {% endif %}
+{% endfor %}
+```
+
+願わくば、少し見つめていただければ、このテンプレートが何を行っているかがわかるかもしれません。
+このテンプレートは、各メッセージの「役割」に基づいて特定のトークンを追加します。これらのトークンは、メッセージを送信した人を表すものです。
+ユーザー、アシスタント、およびシステムメッセージは、それらが含まれるトークンによってモデルによって明確に区別されます。
+
+
+## How do I create a chat template?
+
+簡単です。単純にJinjaテンプレートを書いて、`tokenizer.chat_template`を設定します。
+他のモデルから既存のテンプレートを始点にして、必要に応じて編集すると便利かもしれません!
+例えば、上記のLLaMAテンプレートを取って、アシスタントメッセージに"[ASST]"と"[/ASST]"を追加できます。
+
+```
+{% for message in messages %}
+ {% if message['role'] == 'user' %}
+ {{ bos_token + '[INST] ' + message['content'].strip() + ' [/INST]' }}
+ {% elif message['role'] == 'system' %}
+ {{ '<>\\n' + message['content'].strip() + '\\n< >\\n\\n' }}
+ {% elif message['role'] == 'assistant' %}
+ {{ '[ASST] ' + message['content'] + ' [/ASST]' + eos_token }}
+ {% endif %}
+{% endfor %}
+```
+
+次に、単に`tokenizer.chat_template`属性を設定してください。
+次回、[`~PreTrainedTokenizer.apply_chat_template`]を使用する際に、新しいテンプレートが使用されます!
+この属性は`tokenizer_config.json`ファイルに保存されるため、[`~utils.PushToHubMixin.push_to_hub`]を使用して
+新しいテンプレートをHubにアップロードし、みんなが正しいテンプレートを使用していることを確認できます!
+
+```python
+template = tokenizer.chat_template
+template = template.replace("SYS", "SYSTEM") # Change the system token
+tokenizer.chat_template = template # Set the new template
+tokenizer.push_to_hub("model_name") # Upload your new template to the Hub!
+```
+
+[`~PreTrainedTokenizer.apply_chat_template`] メソッドは、あなたのチャットテンプレートを使用するために `TextGenerationPipeline` クラスによって呼び出されます。
+したがって、正しいチャットテンプレートを設定すると、あなたのモデルは自動的に [`TextGenerationPipeline`] と互換性があるようになります。
+
+
+## What are "default" templates?
+
+チャットテンプレートの導入前に、チャットの処理はモデルクラスレベルでハードコードされていました。
+後方互換性のために、このクラス固有の処理をデフォルトテンプレートとして保持し、クラスレベルで設定されています。
+モデルにチャットテンプレートが設定されていない場合、ただしモデルクラスのデフォルトテンプレートがある場合、
+`TextGenerationPipeline`クラスや`apply_chat_template`などのメソッドはクラステンプレートを使用します。
+トークナイザのデフォルトのチャットテンプレートを確認するには、`tokenizer.default_chat_template`属性をチェックしてください。
+
+これは、後方互換性のために純粋に行っていることで、既存のワークフローを壊さないようにしています。
+モデルにとってクラステンプレートが適切である場合でも、デフォルトテンプレートをオーバーライドして
+`chat_template`属性を明示的に設定することを強くお勧めします。これにより、ユーザーにとって
+モデルがチャット用に正しく構成されていることが明確になり、デフォルトテンプレートが変更されたり廃止された場合に備えることができます。
+
+## What template should I use?
+
+すでにチャットのトレーニングを受けたモデルのテンプレートを設定する場合、テンプレートがトレーニング中にモデルが見たメッセージのフォーマットとまったく一致することを確認する必要があります。
+そうでない場合、性能の低下を経験する可能性が高いです。これはモデルをさらにトレーニングしている場合でも同様です - チャットトークンを一定に保つと、おそらく最高の性能が得られます。
+これはトークン化と非常に類似しており、通常はトレーニング中に使用されたトークン化と正確に一致する場合に、推論またはファインチューニングの際に最良の性能が得られます。
+
+一方、ゼロからモデルをトレーニングするか、チャットのためにベース言語モデルをファインチューニングする場合、適切なテンプレートを選択する自由度があります。
+LLM(Language Model)はさまざまな入力形式を処理できるほどスマートです。クラス固有のテンプレートがないモデル用のデフォルトテンプレートは、一般的なユースケースに対して良い柔軟な選択肢です。
+これは、`ChatMLフォーマット`に従ったもので、多くのユースケースに適しています。次のようになります:
+
+```
+{% for message in messages %}
+ {{'<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n'}}
+{% endfor %}
+```
+
+If you like this one, here it is in one-liner form, ready to copy into your code:
+
+```python
+tokenizer.chat_template = "{% for message in messages %}{{'<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n'}}{% endfor %}"
+```
+
+このテンプレートは、各メッセージを「``」トークンで囲み、役割を文字列として単純に記述します。
+これにより、トレーニングで使用する役割に対する柔軟性が得られます。出力は以下のようになります:
+
+
+```
+<|im_start|>system
+You are a helpful chatbot that will do its best not to say anything so stupid that people tweet about it.<|im_end|>
+<|im_start|>user
+How are you?<|im_end|>
+<|im_start|>assistant
+I'm doing great!<|im_end|>
+```
+
+「ユーザー」、「システム」、および「アシスタント」の役割は、チャットの標準です。
+特に、`TextGenerationPipeline`との連携をスムーズに行う場合には、これらの役割を使用することをお勧めします。ただし、これらの役割に制約はありません。テンプレートは非常に柔軟で、任意の文字列を役割として使用できます。
+
+## I want to use chat templates! How should I get started?
+
+チャットモデルを持っている場合、そのモデルの`tokenizer.chat_template`属性を設定し、[`~PreTrainedTokenizer.apply_chat_template`]を使用してテストする必要があります。
+これはモデルの所有者でない場合でも適用されます。モデルのリポジトリが空のチャットテンプレートを使用している場合、またはデフォルトのクラステンプレートを使用している場合でも、
+この属性を適切に設定できるように[プルリクエスト](https://huggingface.co/docs/hub/repositories-pull-requests-discussions)を開いてください。
+
+一度属性が設定されれば、それで完了です! `tokenizer.apply_chat_template`は、そのモデルに対して正しく動作するようになります。これは、
+`TextGenerationPipeline` などの場所でも自動的にサポートされます。
+
+モデルがこの属性を持つことを確認することで、オープンソースモデルの全コミュニティがそのフルパワーを使用できるようになります。
+フォーマットの不一致はこの分野に悩み続け、パフォーマンスに黙って影響を与えてきました。それを終わらせる時が来ました!
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/community.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/community.md
new file mode 100644
index 0000000000000000000000000000000000000000..ffe28d042d237e6ddfaeec7d554b690d140a7411
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/community.md
@@ -0,0 +1,69 @@
+
+
+# Community
+
+このページは、コミュニティによって開発された🤗 Transformersに関するリソースをまとめたものです。
+
+## Community resources:
+
+| リソース | 説明 | 作者 |
+|:----------|:-------------|------:|
+| [Hugging Face Transformers Glossary Flashcards](https://www.darigovresearch.com/huggingface-transformers-glossary-flashcards) | [Transformers Docs Glossary](glossary)に基づいたフラッシュカードセットです。このセットは、長期の知識定着を特に考慮して設計されたオープンソースのクロスプラットフォームアプリである[Anki](https://apps.ankiweb.net/)を使用して簡単に学習/復習できる形式になっています。[フラッシュカードの使用方法に関する紹介ビデオはこちら](https://www.youtube.com/watch?v=Dji_h7PILrw)をご覧ください。 | [Darigov Research](https://www.darigovresearch.com/) |
+
+## Community notebooks:
+
+| ノートブック | 説明 | 著者 | |
+|:----------|:-------------|:-------------|------:|
+| [事前学習済みのTransformerを微調整して歌詞を生成](https://github.com/AlekseyKorshuk/huggingartists) | GPT-2モデルを微調整してお気に入りのアーティストのスタイルで歌詞を生成する方法 | [Aleksey Korshuk](https://github.com/AlekseyKorshuk) | [](https://colab.research.google.com/github/AlekseyKorshuk/huggingartists/blob/master/huggingartists-demo.ipynb) |
+| [Tensorflow 2でT5をトレーニング](https://github.com/snapthat/TF-T5-text-to-text) | Tensorflow 2を使用して任意のタスクに対してT5をトレーニングする方法。このノートブックはTensorflow 2を使用してSQUADで実装された質問と回答タスクを示しています。 | [Muhammad Harris](https://github.com/HarrisDePerceptron) | [](https://colab.research.google.com/github/snapthat/TF-T5-text-to-text/blob/master/snapthatT5/notebooks/TF-T5-Datasets%20Training.ipynb) |
+| [TPUでT5をトレーニング](https://github.com/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb) | TransformersとNlpを使用してSQUADでT5をトレーニングする方法 | [Suraj Patil](https://github.com/patil-suraj) | [](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb#scrollTo=QLGiFCDqvuil) |
+| [分類と多肢選択のためにT5を微調整](https://github.com/patil-suraj/exploring-T5/blob/master/t5_fine_tuning.ipynb) | PyTorch Lightningを使用してテキスト対テキスト形式でT5を分類と多肢選択タスクに微調整する方法 | [Suraj Patil](https://github.com/patil-suraj) | [](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/t5_fine_tuning.ipynb) |
+| [新しいデータセットと言語でDialoGPTを微調整](https://github.com/ncoop57/i-am-a-nerd/blob/master/_notebooks/2020-05-12-chatbot-part-1.ipynb) | DialoGPTモデルを新しいデータセットでオープンダイアログ会話用の微調整する方法 | [Nathan Cooper](https://github.com/ncoop57) | [](https://colab.research.google.com/github/ncoop57/i-am-a-nerd/blob/master/_notebooks/2020-05-12-chatbot-part-1.ipynb) |
+| [Reformerを使用した長いシーケンスモデリング](https://github.com/patrickvonplaten/notebooks/blob/master/PyTorch_Reformer.ipynb) | Reformerを使用して500,000トークンまでのシーケンスをトレーニングする方法 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/PyTorch_Reformer.ipynb) |
+| [要約のためにBARTを微調整](https://github.com/ohmeow/ohmeow_website/blob/master/posts/2021-05-25-mbart-sequence-classification-with-blurr.ipynb) | Blurrを使用して要約のためにBARTを微調整する方法 | [Wayde Gilliam](https://ohmeow.com/) | [](https://colab.research.google.com/github/ohmeow/ohmeow_website/blob/master/posts/2021-05-25-mbart-sequence-classification-with-blurr.ipynb) |
+| [事前学習済みのTransformerを微調整して誰かのツイートを生成](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb) | GPT-2モデルを微調整してお気に入りのTwitterアカウントのスタイルでツイートを生成する方法 | [Boris Dayma](https://github.com/borisdayma) | [](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb) |
+| [🤗 Hugging FaceモデルをWeights & Biasesで最適化](https://colab.research.google.com/github/wandb/examples/blob/master/colabs/huggingface/Optimize_Hugging_Face_models_with_Weights_%26_Biases.ipynb) | Hugging FaceとWeights & Biasesの統合を示す完全なチュートリアル | [Boris Dayma](https://github.com/borisdayma) | [](https://colab.research.google.com/github/wandb/examples/blob/master/colabs/huggingface/Optimize_Hugging_Face_models_with_Weights_%26_Biases.ipynb) |
+| [Longformerの事前学習](https://github.com/allenai/longformer/blob/master/scripts/convert_model_to_long.ipynb) | 既存の事前学習済みモデルの「長い」バージョンを構築する方法 | [Iz Beltagy](https://beltagy.net) | [](https://colab.research.google.com/github/allenai/longformer/blob/master/scripts/convert_model_to_long.ipynb) |
+| [QAタスクのためにLongformerを微調整](https://github.com/patil-suraj/Notebooks/blob/master/longformer_qa_training.ipynb) | QAタスクのためにLongformerモデルを微調整する方法 | [Suraj Patil](https://github.com/patil-suraj) | [](https://colab.research.google.com/github/patil-suraj/Notebooks/blob/master/longformer_qa_training.ipynb) |
+| [🤗nlpを使用したモデルの評価](https://github.com/patrickvonplaten/notebooks/blob/master/How_to_evaluate_Longformer_on_TriviaQA_using_NLP.ipynb) | `nlp`を使用してTriviaQAでLongformerを評価する方法 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/drive/1m7eTGlPmLRgoPkkA7rkhQdZ9ydpmsdLE?usp=sharing) |
+| [感情スパン抽出のためにT5を微調整](https://github.com/enzoampil/t5-intro/blob/master/t5_qa_training_pytorch_span_extraction.ipynb) | PyTorch Lightningを使用して感情スパン抽出のためにT5を微調整する方法 | [Lorenzo Ampil](https://github.com/enzoampil) | [](https://colab.research.google.com/github/enzoampil/t5-intro/blob/master/t5_qa_training_pytorch_span_extraction.ipynb) |
+| [DistilBertをマルチクラス分類にファインチューニング](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_multiclass_classification.ipynb) | PyTorchを使用してDistilBertをマルチクラス分類にファインチューニングする方法 | [Abhishek Kumar Mishra](https://github.com/abhimishra91) | [](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_multiclass_classification.ipynb)|
+|[BERTをマルチラベル分類にファインチューニング](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_multi_label_classification.ipynb)|PyTorchを使用してBERTをマルチラベル分類にファインチューニングする方法|[Abhishek Kumar Mishra](https://github.com/abhimishra91) |[](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_multi_label_classification.ipynb)|
+|[T5を要約にファインチューニング](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_summarization_wandb.ipynb)|PyTorchを使用してT5を要約にファインチューニングし、WandBで実験をトラッキングする方法|[Abhishek Kumar Mishra](https://github.com/abhimishra91) |[](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_summarization_wandb.ipynb)|
+|[ダイナミックパディング/バケッティングを使用してTransformersのファインチューニングを高速化](https://github.com/ELS-RD/transformers-notebook/blob/master/Divide_Hugging_Face_Transformers_training_time_by_2_or_more.ipynb)|ダイナミックパディング/バケッティングを使用してファインチューニングを2倍高速化する方法|[Michael Benesty](https://github.com/pommedeterresautee) |[](https://colab.research.google.com/drive/1CBfRU1zbfu7-ijiOqAAQUA-RJaxfcJoO?usp=sharing)|
+|[マスク言語モデリングのためのReformerの事前学習](https://github.com/patrickvonplaten/notebooks/blob/master/Reformer_For_Masked_LM.ipynb)|双方向セルフアテンションレイヤーを備えたReformerモデルのトレーニング方法|[Patrick von Platen](https://github.com/patrickvonplaten) |[](https://colab.research.google.com/drive/1tzzh0i8PgDQGV3SMFUGxM7_gGae3K-uW?usp=sharing)|
+|[Sci-BERTを拡張してファインチューニング](https://github.com/lordtt13/word-embeddings/blob/master/COVID-19%20Research%20Data/COVID-SciBERT.ipynb)|AllenAIのCORDデータセットで事前学習済みのSciBERTモデルの語彙を拡張し、パイプライン化する方法|[Tanmay Thakur](https://github.com/lordtt13) |[](https://colab.research.google.com/drive/1rqAR40goxbAfez1xvF3hBJphSCsvXmh8)|
+|[Trainer APIを使用してBlenderBotSmallを要約のためにファインチューニング](https://github.com/lordtt13/transformers-experiments/blob/master/Custom%20Tasks/fine-tune-blenderbot_small-for-summarization.ipynb)|カスタムデータセットでBlenderBotSmallを要約のためにファインチューニングする方法、Trainer APIを使用|[Tanmay Thakur](https://github.com/lordtt13) |[](https://colab.research.google.com/drive/19Wmupuls7mykSGyRN_Qo6lPQhgp56ymq?usp=sharing)|
+|[ElectraをファインチューニングしてCaptum Integrated Gradientsで解釈](https://github.com/elsanns/xai-nlp-notebooks/blob/master/electra_fine_tune_interpret_captum_ig.ipynb) |Electraを感情分析のためにファインチューニングし、Captum Integrated Gradientsで予測を解釈する方法|[Eliza Szczechla](https://elsanns.github.io) |[](https://colab.research.google.com/github/elsanns/xai-nlp-notebooks/blob/master/electra_fine_tune_interpret_captum_ig.ipynb)|
+|[Trainerクラスを使用して非英語のGPT-2モデルをファインチューニング](https://github.com/philschmid/fine-tune-GPT-2/blob/master/Fine_tune_a_non_English_GPT_2_Model_with_Huggingface.ipynb) |Trainerクラスを使用して非英語のGPT-2モデルをファインチューニングする方法|[Philipp Schmid](https://www.philschmid.de) |[](https://colab.research.google.com/github/philschmid/fine-tune-GPT-2/blob/master/Fine_tune_a_non_English_GPT_2_Model_with_Huggingface.ipynb)|
+|[DistilBERTモデルをマルチラベル分類タスクのためにファインチューニング](https://github.com/DhavalTaunk08/Transformers_scripts/blob/master/Transformers_multilabel_distilbert.ipynb) |DistilBERTモデルをマルチラベル分類タスクのためにファインチューニングする方法|[Dhaval Taunk](https://github.com/DhavalTaunk08) |[](https://colab.research.google.com/github/DhavalTaunk08/Transformers_scripts/blob/master/Transformers_multilabel_distilbert.ipynb)|
+|[ALBERTを文ペア分類タスクのためにファインチューニング](https://github.com/NadirEM/nlp-notebooks/blob/master/Fine_tune_ALBERT_sentence_pair_classification.ipynb) |ALBERTモデルまたは他のBERTベースのモデルを文ペア分類タスクのためにファインチューニングする方法|[Nadir El Manouzi](https://github.com/NadirEM) |[](https://colab.research.google.com/github/NadirEM/nlp-notebooks/blob/master/Fine_tune_ALBERT_sentence_pair_classification.ipynb)|
+|[RoBERTaを感情分析のためにファインチューニング](https://github.com/DhavalTaunk08/NLP_scripts/blob/master/sentiment_analysis_using_roberta.ipynb) |RoBERTaモデルを感情分析のためにファインチューニングする方法|[Dhaval Taunk](https://github.com/DhavalTaunk08) |[](https://colab.research.google.com/github/DhavalTaunk08/NLP_scripts/blob/master/sentiment_analysis_using_roberta.ipynb)|
+|[質問生成モデルの評価](https://github.com/flexudy-pipe/qugeev) | seq2seqトランスフォーマーモデルによって生成された質問の回答の正確さを評価する方法 | [Pascal Zoleko](https://github.com/zolekode) | [](https://colab.research.google.com/drive/1bpsSqCQU-iw_5nNoRm_crPq6FRuJthq_?usp=sharing)|
+|[DistilBERTとTensorflowを使用してテキストを分類](https://github.com/peterbayerle/huggingface_notebook/blob/main/distilbert_tf.ipynb) | TensorFlowでテキスト分類のためにDistilBERTをファインチューニングする方法 | [Peter Bayerle](https://github.com/peterbayerle) | [](https://colab.research.google.com/github/peterbayerle/huggingface_notebook/blob/main/distilbert_tf.ipynb)|
+|[CNN/Dailymailでのエンコーダーデコーダー要約にBERTを活用](https://github.com/patrickvonplaten/notebooks/blob/master/BERT2BERT_for_CNN_Dailymail.ipynb) | *google-bert/bert-base-uncased* チェックポイントを使用してCNN/Dailymailの要約のために *EncoderDecoderModel* をウォームスタートする方法 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/BERT2BERT_for_CNN_Dailymail.ipynb)|
+|[BBC XSumでのエンコーダーデコーダー要約にRoBERTaを活用](https://github.com/patrickvonplaten/notebooks/blob/master/RoBERTaShared_for_BBC_XSum.ipynb) | *FacebookAI/roberta-base* チェックポイントを使用してBBC/XSumの要約のための共有 *EncoderDecoderModel* をウォームスタートする方法 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/RoBERTaShared_for_BBC_XSum.ipynb)|
+|[TAPASをシーケンシャル質問応答(SQA)でファインチューニング](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) | シーケンシャル質問応答(SQA)データセットで *tapas-base* チェックポイントを使用して *TapasForQuestionAnswering* をファインチューニングする方法 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb)|
+|[TabFactでTAPASを評価](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Evaluating_TAPAS_on_the_Tabfact_test_set.ipynb) | *tapas-base-finetuned-tabfact* チェックポイントを使用してファインチューニングされた *TapasForSequenceClassification* を評価する方法、🤗 datasets と 🤗 transformers ライブラリを組み合わせて使用 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Evaluating_TAPAS_on_the_Tabfact_test_set.ipynb)|
+|[翻訳のためのmBARTをファインチューニング](https://colab.research.google.com/github/vasudevgupta7/huggingface-tutorials/blob/main/translation_training.ipynb) | Seq2SeqTrainerを使用してHindiからEnglishへの翻訳のためにmBARTをファインチューニングする方法 | [Vasudev Gupta](https://github.com/vasudevgupta7) | [](https://colab.research.google.com/github/vasudevgupta7/huggingface-tutorials/blob/main/translation_training.ipynb)|
+|[FUNSD(フォーム理解データセット)でLayoutLMをファインチューニング](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb) | スキャンされたドキュメントからの情報抽出のためにFUNSDデータセットで *LayoutLMForTokenClassification* をファインチューニングする方法 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb)|
+| [DistilGPT2のファインチューニングとテキスト生成](https://colab.research.google.com/github/tripathiaakash/DistilGPT2-Tutorial/blob/main/distilgpt2_fine_tuning.ipynb) | DistilGPT2のファインチューニングとテキスト生成方法 | [Aakash Tripathi](https://github.com/tripathiaakash) | [](https://colab.research.google.com/github/tripathiaakash/DistilGPT2-Tutorial/blob/main/distilgpt2_fine_tuning.ipynb)|
+| [最大8KトークンでのLEDのファインチューニング](https://github.com/patrickvonplaten/notebooks/blob/master/Fine_tune_Longformer_Encoder_Decoder_(LED)_for_Summarization_on_pubmed.ipynb) | ロングレンジ要約のためのpubmedでLEDをファインチューニングする方法 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/Fine_tune_Longformer_Encoder_Decoder_(LED)_for_Summarization_on_pubmed.ipynb)|
+| [ArxivでのLEDの評価](https://github.com/patrickvonplaten/notebooks/blob/master/LED_on_Arxiv.ipynb) | ロングレンジ要約のためのLEDの効果的な評価方法 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/LED_on_Arxiv.ipynb)|
+| [RVL-CDIP(文書画像分類データセット)でのLayoutLMのファインチューニング](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb) | スキャンされた文書の分類のためのRVL-CDIPデータセットで*LayoutLMForSequenceClassification*をファインチューニングする方法 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb)|
+| [Wav2Vec2 CTCデコーディングとGPT2の調整](https://github.com/voidful/huggingface_notebook/blob/main/xlsr_gpt.ipynb) | 言語モデルの調整を伴うCTCシーケンスのデコーディング方法 | [Eric Lam](https://github.com/voidful) | [](https://colab.research.google.com/drive/1e_z5jQHYbO2YKEaUgzb1ww1WwiAyydAj?usp=sharing)|
+| [Trainerクラスを使用した2言語の要約用にBARTをファインチューニング](https://github.com/elsanns/xai-nlp-notebooks/blob/master/fine_tune_bart_summarization_two_langs.ipynb) | トレーナークラスを使用して2つの言語での要約用にBARTをファインチューニングする方法 | [Eliza Szczechla](https://github.com/elsanns) | [](https://colab.research.google.com/github/elsanns/xai-nlp-notebooks/blob/master/fine_tune_bart_summarization_two_langs.ipynb)|
+| [PubMedデータセットでBigBirdの評価](https://github.com/patrickvonplaten/notebooks/blob/master/Evaluating_Big_Bird_on_TriviaQA.ipynb) | Trivia QAの長いドキュメント質問応答でBigBirdの評価方法 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/Evaluating_Big_Bird_on_TriviaQA.ipynb)|
+| [Wav2Vec2を使用してビデオの字幕を作成する](https://github.com/Muennighoff/ytclipcc/blob/main/wav2vec_youtube_captions.ipynb) | Wav2Vecでオーディオを転記して任意のビデオからYouTubeの字幕を作成する方法 | [Niklas Muennighoff](https://github.com/Muennighoff) |[](https://colab.research.google.com/github/Muennighoff/ytclipcc/blob/main/wav2vec_youtube_captions.ipynb) |
+| [PyTorch Lightningを使用したCIFAR-10でのVision Transformerのファインチューニング](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_PyTorch_Lightning.ipynb) | HuggingFace Transformers、Datasets、およびPyTorch Lightningを使用してCIFAR-10でVision Transformer(ViT)をファインチューニングする方法 | [Niels Rogge](https://github.com/nielsrogge) |[](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_PyTorch_Lightning.ipynb) |
+| [🤗 Trainerを使用したCIFAR-10でのVision Transformerのファインチューニング](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_the_%F0%9F%A4%97_Trainer.ipynb) | HuggingFace Transformers、Datasets、および🤗 Trainerを使用してCIFAR-10でVision Transformer(ViT)をファインチューニングする方法 | [Niels Rogge](https://github.com/nielsrogge) |[](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_the_%F0%9F%A4%97_Trainer.ipynb) |
+| [Open Entity、エンティティタイピングデータセットでLUKEの評価](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_open_entity.ipynb) | Open Entityデータセットで*LukeForEntityClassification*の評価方法 | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_open_entity.ipynb) |
+| [TACRED、関係抽出データセットでLUKEの評価](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_tacred.ipynb) | TACREDデータセットで*LukeForEntityPairClassification*の評価方法 | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_tacred.ipynb) |
+| [CoNLL-2003、重要なNERベンチマークでLUKEの評価](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_conll_2003.ipynb) | CoNLL-2003データセットで*LukeForEntitySpanClassification*の評価方法 | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_conll_2003.ipynb) |
+| [PubMedデータセットでBigBird-Pegasusの評価](https://github.com/vasudevgupta7/bigbird/blob/main/notebooks/bigbird_pegasus_evaluation.ipynb) | PubMedデータセットで*BigBirdPegasusForConditionalGeneration*の評価方法 | [Vasudev Gupta](https://github.com/vasudevgupta7) | [](https://colab.research.google.com/github/vasudevgupta7/bigbird/blob/main/notebooks/bigbird_pegasus_evaluation.ipynb) |
+| [Wav2Vec2を使用したスピーチエモーション分類](https://github/m3hrdadfi/soxan/blob/main/notebooks/Emotion_recognition_in_Greek_speech_using_Wav2Vec2.ipynb) | MEGAデータセットでの感情分類のための事前学習済みWav2Vec2モデルの利用方法 | [Mehrdad Farahani](https://github.com/m3hrdadfi) | [](https://colab.research.google.com/github/m3hrdadfi/soxan/blob/main/notebooks/Emotion_recognition_in_Greek_speech_using_Wav2Vec2.ipynb) |
+| [DETRを使用して画像内のオブジェクトを検出する](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/DETR/DETR_minimal_example_(with_DetrFeatureExtractor).ipynb) | トレーニング済み*DetrForObjectDetection*モデルを使用して画像内のオブジェクトを検出し、注意を可視化する方法 | [Niels Rogge](https://github.com/NielsRogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/DETR/DETR_minimal_example_(with_DetrFeatureExtractor).ipynb) |
+| [カスタムオブジェクト検出データセットでDETRをファインチューニングする](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/DETR/Fine_tuning_DetrForObjectDetection_on_custom_dataset_(balloon).ipynb) | カスタムオブジェクト検出データセットで*DetrForObjectDetection*をファインチューニングする方法 | [Niels Rogge](https://github.com/NielsRogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/DETR/Fine_tuning_DetrForObjectDetection_on_custom_dataset_(balloon).ipynb) |
+| [Named Entity RecognitionのためにT5をファインチューニング](https://github.com/ToluClassics/Notebooks/blob/main/T5_Ner_Finetuning.ipynb) | Named Entity RecognitionタスクでT5をファインチューニングする方法 | [Ogundepo Odunayo](https://github.com/ToluClassics) | [](https://colab.research.google.com/drive/1obr78FY_cBmWY5ODViCmzdY6O1KB65Vc?usp=sharing) |
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/create_a_model.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/create_a_model.md
new file mode 100644
index 0000000000000000000000000000000000000000..fdb23f98e7b1077631f034290f69718421749e1a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/create_a_model.md
@@ -0,0 +1,420 @@
+
+
+# Create a custom architecture
+
+[`AutoClass`](model_doc/auto)は、モデルのアーキテクチャを自動的に推論し、事前学習済みの設定と重みをダウンロードします。一般的には、チェックポイントに依存しないコードを生成するために`AutoClass`を使用することをお勧めします。ただし、特定のモデルパラメータに対する制御をより詳細に行いたいユーザーは、いくつかの基本クラスからカスタム🤗 Transformersモデルを作成できます。これは、🤗 Transformersモデルを研究、トレーニング、または実験する興味があるユーザーに特に役立つかもしれません。このガイドでは、`AutoClass`を使用しないカスタムモデルの作成について詳しく説明します。次の方法を学びます:
+
+- モデルの設定をロードおよびカスタマイズする。
+- モデルアーキテクチャを作成する。
+- テキスト用の遅いトークナイザと高速トークナイザを作成する。
+- ビジョンタスク用の画像プロセッサを作成する。
+- オーディオタスク用の特徴抽出器を作成する。
+- マルチモーダルタスク用のプロセッサを作成する。
+
+## Configuration
+
+[設定](main_classes/configuration)は、モデルの特定の属性を指します。各モデルの設定には異なる属性があります。たとえば、すべてのNLPモデルには、`hidden_size`、`num_attention_heads`、`num_hidden_layers`、および`vocab_size`属性が共通してあります。これらの属性は、モデルを構築するための注意ヘッドの数や隠れ層の数を指定します。
+
+[DistilBERT](model_doc/distilbert)をより詳しく調べるために、[`DistilBertConfig`]にアクセスしてその属性を調べてみましょう:
+
+```py
+>>> from transformers import DistilBertConfig
+
+>>> config = DistilBertConfig()
+>>> print(config)
+DistilBertConfig {
+ "activation": "gelu",
+ "attention_dropout": 0.1,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+[`DistilBertConfig`]は、基本の[`DistilBertModel`]を構築するために使用されるすべてのデフォルト属性を表示します。
+すべての属性はカスタマイズ可能で、実験のためのスペースを提供します。例えば、デフォルトのモデルをカスタマイズして以下のようなことができます:
+
+- `activation`パラメータで異なる活性化関数を試す。
+- `attention_dropout`パラメータで注意確率の高いドロップアウト率を使用する。
+
+
+```py
+>>> my_config = DistilBertConfig(activation="relu", attention_dropout=0.4)
+>>> print(my_config)
+DistilBertConfig {
+ "activation": "relu",
+ "attention_dropout": 0.4,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+事前学習済みモデルの属性は、[`~PretrainedConfig.from_pretrained`] 関数で変更できます:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("distilbert/distilbert-base-uncased", activation="relu", attention_dropout=0.4)
+```
+
+Once you are satisfied with your model configuration, you can save it with [`PretrainedConfig.save_pretrained`]. Your configuration file is stored as a JSON file in the specified save directory.
+
+```py
+>>> my_config.save_pretrained(save_directory="./your_model_save_path")
+```
+
+設定ファイルを再利用するには、[`~PretrainedConfig.from_pretrained`]を使用してそれをロードします:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/config.json")
+```
+
+
+
+カスタム構成ファイルを辞書として保存することも、カスタム構成属性とデフォルトの構成属性の違いだけを保存することもできます!詳細については[configuration](main_classes/configuration)のドキュメンテーションをご覧ください。
+
+
+
+## Model
+
+次のステップは、[モデル](main_classes/models)を作成することです。モデル(アーキテクチャとも緩く言われることがあります)は、各レイヤーが何をしているか、どの操作が行われているかを定義します。構成からの `num_hidden_layers` のような属性はアーキテクチャを定義するために使用されます。
+すべてのモデルは [`PreTrainedModel`] をベースクラスとし、入力埋め込みのリサイズやセルフアテンションヘッドのプルーニングなど、共通のメソッドがいくつかあります。
+さらに、すべてのモデルは [`torch.nn.Module`](https://pytorch.org/docs/stable/generated/torch.nn.Module.html)、[`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model)、または [`flax.linen.Module`](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html) のいずれかのサブクラスでもあります。つまり、モデルはそれぞれのフレームワークの使用法と互換性があります。
+
+
+
+モデルにカスタム構成属性をロードします:
+
+```py
+>>> from transformers import DistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/config.json")
+>>> model = DistilBertModel(my_config)
+```
+
+これにより、事前トレーニング済みの重みではなくランダムな値を持つモデルが作成されます。
+これは、トレーニングが行われるまで、まだ有用なものとして使用することはできません。
+トレーニングはコストと時間がかかるプロセスです。
+通常、トレーニングに必要なリソースの一部しか使用せず、より速くより良い結果を得るために事前学習済みモデルを使用することが良いでしょう。
+
+[`~PreTrainedModel.from_pretrained`]を使用して事前学習済みモデルを作成します:
+
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+事前学習済みの重みをロードする際、モデルが🤗 Transformersによって提供されている場合、デフォルトのモデル設定が自動的にロードされます。ただし、必要に応じてデフォルトのモデル設定属性の一部またはすべてを独自のもので置き換えることができます。
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+モデルにカスタム設定属性をロードしてください:
+
+```py
+>>> from transformers import TFDistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+>>> tf_model = TFDistilBertModel(my_config)
+```
+
+これにより、事前学習済みの重みではなくランダムな値を持つモデルが作成されます。
+このモデルを有用な目的にはまだ使用することはできません。トレーニングはコストがかかり、時間がかかるプロセスです。
+一般的には、トレーニングに必要なリソースの一部しか使用せずに、より速く優れた結果を得るために事前学習済みモデルを使用することが良いでしょう。
+
+[`~TFPreTrainedModel.from_pretrained`]を使用して事前学習済みモデルを作成します:
+
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+事前学習済みの重みをロードする際、モデルが🤗 Transformersによって提供されている場合、デフォルトのモデル構成が自動的にロードされます。ただし、必要であればデフォルトのモデル構成属性の一部またはすべてを独自のもので置き換えることもできます:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+
+
+### Model heads
+
+この時点で、ベースのDistilBERTモデルがあり、これは隠れた状態を出力します。隠れた状態はモデルのヘッドへの入力として渡され、最終的な出力を生成します。🤗 Transformersは、モデルがそのタスクをサポートしている限り、各タスクに対応する異なるモデルヘッドを提供します(つまり、DistilBERTを翻訳のようなシーケンス対シーケンスタスクに使用することはできません)。
+
+
+
+たとえば、[`DistilBertForSequenceClassification`]は、シーケンス分類ヘッドを持つベースのDistilBERTモデルです。シーケンス分類ヘッドは、プールされた出力の上にある線形層です。
+
+```py
+>>> from transformers import DistilBertForSequenceClassification
+
+>>> model = DistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+新しいタスクにこのチェックポイントを簡単に再利用するには、異なるモデルヘッドに切り替えます。
+質問応答タスクの場合、[`DistilBertForQuestionAnswering`] モデルヘッドを使用します。
+質問応答ヘッドはシーケンス分類ヘッドと類似していますが、隠れ状態の出力の上に線形層があります。
+
+```py
+>>> from transformers import DistilBertForQuestionAnswering
+
+>>> model = DistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+例えば、[`TFDistilBertForSequenceClassification`]は、シーケンス分類ヘッドを持つベースのDistilBERTモデルです。シーケンス分類ヘッドは、プールされた出力の上にある線形層です。
+
+```py
+>>> from transformers import TFDistilBertForSequenceClassification
+
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+別のタスクにこのチェックポイントを簡単に再利用することができ、異なるモデルヘッドに切り替えるだけです。
+質問応答タスクの場合、[`TFDistilBertForQuestionAnswering`]モデルヘッドを使用します。
+質問応答ヘッドはシーケンス分類ヘッドと似ていますが、隠れ状態の出力の上に線形層があるだけです。
+
+
+```py
+>>> from transformers import TFDistilBertForQuestionAnswering
+
+>>> tf_model = TFDistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+## Tokenizer
+
+テキストデータをモデルで使用する前に必要な最後のベースクラスは、生のテキストをテンソルに変換するための[トークナイザ](main_classes/tokenizer)です。
+🤗 Transformersで使用できる2つのタイプのトークナイザがあります:
+
+- [`PreTrainedTokenizer`]: トークナイザのPython実装です。
+- [`PreTrainedTokenizerFast`]: Rustベースの[🤗 Tokenizer](https://huggingface.co/docs/tokenizers/python/latest/)ライブラリからのトークナイザです。
+このトークナイザのタイプは、そのRust実装により、特にバッチトークナイゼーション中に高速です。
+高速なトークナイザは、トークンを元の単語または文字にマッピングする*オフセットマッピング*などの追加メソッドも提供します。
+
+両方のトークナイザは、エンコードとデコード、新しいトークンの追加、特別なトークンの管理など、共通のメソッドをサポートしています。
+
+
+
+すべてのモデルが高速なトークナイザをサポートしているわけではありません。
+モデルが高速なトークナイザをサポートしているかどうかを確認するには、この[表](index#supported-frameworks)をご覧ください。
+
+
+
+独自のトークナイザをトレーニングした場合、*ボキャブラリー*ファイルからトークナイザを作成できます。
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> my_tokenizer = DistilBertTokenizer(vocab_file="my_vocab_file.txt", do_lower_case=False, padding_side="left")
+```
+
+カスタムトークナイザーから生成される語彙は、事前学習済みモデルのトークナイザーが生成する語彙とは異なることを覚えておくことは重要です。
+事前学習済みモデルを使用する場合は、事前学習済みモデルの語彙を使用する必要があります。そうしないと、入力が意味をなさなくなります。
+[`DistilBertTokenizer`]クラスを使用して、事前学習済みモデルの語彙を持つトークナイザーを作成します:
+
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> slow_tokenizer = DistilBertTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+[`DistilBertTokenizerFast`]クラスを使用して高速なトークナイザを作成します:
+
+```py
+>>> from transformers import DistilBertTokenizerFast
+
+>>> fast_tokenizer = DistilBertTokenizerFast.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+デフォルトでは、[`AutoTokenizer`]は高速なトークナイザを読み込もうとします。`from_pretrained`内で`use_fast=False`を設定することで、この動作を無効にすることができます。
+
+
+
+## Image Processor
+
+画像プロセッサはビジョン入力を処理します。これは基本クラス [`~image_processing_utils.ImageProcessingMixin`] を継承しています。
+
+使用するには、使用しているモデルに関連付けられた画像プロセッサを作成します。
+たとえば、画像分類に[ViT](model_doc/vit)を使用する場合、デフォルトの [`ViTImageProcessor`] を作成します。
+
+```py
+>>> from transformers import ViTImageProcessor
+
+>>> vit_extractor = ViTImageProcessor()
+>>> print(vit_extractor)
+ViTImageProcessor {
+ "do_normalize": true,
+ "do_resize": true,
+ "image_processor_type": "ViTImageProcessor",
+ "image_mean": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": 2,
+ "size": 224
+}
+```
+
+
+
+カスタマイズを必要としない場合、モデルのデフォルトの画像プロセッサパラメータをロードするには、単純に`from_pretrained`メソッドを使用してください。
+
+
+
+[`ViTImageProcessor`]のパラメータを変更して、カスタムの画像プロセッサを作成できます:
+
+
+```py
+>>> from transformers import ViTImageProcessor
+
+>>> my_vit_extractor = ViTImageProcessor(resample="PIL.Image.BOX", do_normalize=False, image_mean=[0.3, 0.3, 0.3])
+>>> print(my_vit_extractor)
+ViTImageProcessor {
+ "do_normalize": false,
+ "do_resize": true,
+ "image_processor_type": "ViTImageProcessor",
+ "image_mean": [
+ 0.3,
+ 0.3,
+ 0.3
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": "PIL.Image.BOX",
+ "size": 224
+}
+```
+
+## Feature Extractor
+
+フィーチャー抽出器は音声入力を処理します。これは基本的な [`~feature_extraction_utils.FeatureExtractionMixin`] クラスから継承され、音声入力を処理するための [`SequenceFeatureExtractor`] クラスからも継承されることがあります。
+
+使用するには、モデルに関連付けられたフィーチャー抽出器を作成します。たとえば、音声分類に [Wav2Vec2](model_doc/wav2vec2) を使用する場合、デフォルトの [`Wav2Vec2FeatureExtractor`] を作成します。
+
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> w2v2_extractor = Wav2Vec2FeatureExtractor()
+>>> print(w2v2_extractor)
+Wav2Vec2FeatureExtractor {
+ "do_normalize": true,
+ "feature_extractor_type": "Wav2Vec2FeatureExtractor",
+ "feature_size": 1,
+ "padding_side": "right",
+ "padding_value": 0.0,
+ "return_attention_mask": false,
+ "sampling_rate": 16000
+}
+```
+
+
+
+カスタマイズを行わない場合、モデルのデフォルトの特徴抽出器パラメーターをロードするには、単に `from_pretrained` メソッドを使用してください。
+
+
+
+[`Wav2Vec2FeatureExtractor`] のパラメーターを変更して、カスタム特徴抽出器を作成できます:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> w2v2_extractor = Wav2Vec2FeatureExtractor(sampling_rate=8000, do_normalize=False)
+>>> print(w2v2_extractor)
+Wav2Vec2FeatureExtractor {
+ "do_normalize": false,
+ "feature_extractor_type": "Wav2Vec2FeatureExtractor",
+ "feature_size": 1,
+ "padding_side": "right",
+ "padding_value": 0.0,
+ "return_attention_mask": false,
+ "sampling_rate": 8000
+}
+```
+
+## Processor
+
+マルチモーダルタスクをサポートするモデルに対して、🤗 Transformersは便利なプロセッサクラスを提供しています。
+このプロセッサクラスは、特徴量抽出器やトークナイザなどの処理クラスを便利にラップし、単一のオブジェクトに結合します。
+たとえば、自動音声認識タスク(ASR)用に[`Wav2Vec2Processor`]を使用してみましょう。
+ASRは音声をテキストに転写するタスクであり、音声入力を処理するために特徴量抽出器とトークナイザが必要です。
+
+音声入力を処理する特徴量抽出器を作成します:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> feature_extractor = Wav2Vec2FeatureExtractor(padding_value=1.0, do_normalize=True)
+```
+
+テキスト入力を処理するトークナイザを作成します:
+
+```py
+>>> from transformers import Wav2Vec2CTCTokenizer
+
+>>> tokenizer = Wav2Vec2CTCTokenizer(vocab_file="my_vocab_file.txt")
+```
+
+[`Wav2Vec2Processor`]で特徴量抽出器とトークナイザを組み合わせます:
+
+
+```py
+>>> from transformers import Wav2Vec2Processor
+
+>>> processor = Wav2Vec2Processor(feature_extractor=feature_extractor, tokenizer=tokenizer)
+```
+
+二つの基本クラス - 設定とモデル - および追加の前処理クラス(トークナイザ、画像プロセッサ、特徴抽出器、またはプロセッサ)を使用することで、🤗 Transformers がサポートするモデルのいずれかを作成できます。これらの基本クラスは設定可能で、必要な特性を使用できます。モデルをトレーニング用に簡単にセットアップしたり、既存の事前学習済みモデルを微調整することができます。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/custom_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/custom_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..588e804494e556861f40d0292d5d5a0259fe1ced
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/custom_models.md
@@ -0,0 +1,336 @@
+
+
+# Sharing custom models
+
+🤗 Transformersライブラリは、簡単に拡張できるように設計されています。すべてのモデルはリポジトリの特定のサブフォルダに完全にコード化されており、抽象化はありません。したがって、モデリングファイルをコピーして調整することが簡単です。
+
+新しいモデルを書いている場合、ゼロから始める方が簡単かもしれません。このチュートリアルでは、カスタムモデルとその設定をどのように書き、Transformers内で使用できるようにし、コードに依存する共同体と共有する方法を説明します。ライブラリに存在しない場合でも、誰でも使用できるようにします。
+
+これを実証するために、[timmライブラリ](https://github.com/rwightman/pytorch-image-models)のResNetクラスを[`PreTrainedModel`]にラップすることによって、ResNetモデルを使用します。
+
+## Writing a custom configuration
+
+モデルに取り組む前に、まずその設定を書きましょう。モデルの設定は、モデルを構築するために必要なすべての情報を含むオブジェクトです。次のセクションで見るように、モデルは初期化するために`config`しか受け取ることができないため、そのオブジェクトができるだけ完全である必要があります。
+
+この例では、ResNetクラスのいくつかの引数を取得し、調整したいかもしれないとします。異なる設定は、異なるタイプのResNetを提供します。その後、これらの引数を確認した後、それらの引数を単に格納します。
+
+```python
+from transformers import PretrainedConfig
+from typing import List
+
+
+class ResnetConfig(PretrainedConfig):
+ model_type = "resnet"
+
+ def __init__(
+ self,
+ block_type="bottleneck",
+ layers: List[int] = [3, 4, 6, 3],
+ num_classes: int = 1000,
+ input_channels: int = 3,
+ cardinality: int = 1,
+ base_width: int = 64,
+ stem_width: int = 64,
+ stem_type: str = "",
+ avg_down: bool = False,
+ **kwargs,
+ ):
+ if block_type not in ["basic", "bottleneck"]:
+ raise ValueError(f"`block_type` must be 'basic' or bottleneck', got {block_type}.")
+ if stem_type not in ["", "deep", "deep-tiered"]:
+ raise ValueError(f"`stem_type` must be '', 'deep' or 'deep-tiered', got {stem_type}.")
+
+ self.block_type = block_type
+ self.layers = layers
+ self.num_classes = num_classes
+ self.input_channels = input_channels
+ self.cardinality = cardinality
+ self.base_width = base_width
+ self.stem_width = stem_width
+ self.stem_type = stem_type
+ self.avg_down = avg_down
+ super().__init__(**kwargs)
+```
+
+重要なことを3つ覚えておくべきポイントは次のとおりです:
+- `PretrainedConfig` を継承する必要があります。
+- あなたの `PretrainedConfig` の `__init__` は任意の kwargs を受け入れる必要があります。
+- これらの `kwargs` は親クラスの `__init__` に渡す必要があります。
+
+継承は、🤗 Transformers ライブラリのすべての機能を取得できるようにするためです。他の2つの制約は、
+`PretrainedConfig` が設定しているフィールド以外にも多くのフィールドを持っていることから来ています。
+`from_pretrained` メソッドで設定を再ロードする場合、これらのフィールドはあなたの設定に受け入れられ、
+その後、親クラスに送信される必要があります。
+
+設定の `model_type` を定義すること(ここでは `model_type="resnet"`)は、
+自動クラスにモデルを登録したい場合を除いては必須ではありません(最後のセクションを参照)。
+
+これで、ライブラリの他のモデル設定と同様に、設定を簡単に作成して保存できます。
+以下は、resnet50d 設定を作成して保存する方法の例です:
+
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d_config.save_pretrained("custom-resnet")
+```
+
+これにより、`custom-resnet` フォルダ内に `config.json` という名前のファイルが保存されます。その後、`from_pretrained` メソッドを使用して構成を再ロードできます。
+
+
+```py
+resnet50d_config = ResnetConfig.from_pretrained("custom-resnet")
+```
+
+また、[`PretrainedConfig`] クラスの他のメソッドを使用することもできます。たとえば、[`~PretrainedConfig.push_to_hub`] を使用して、設定を直接 Hub にアップロードできます。
+
+## Writing a custom model
+
+ResNet の設定ができたので、モデルを書き始めることができます。実際には2つのモデルを書きます。1つはバッチの画像から隠れた特徴を抽出するモデル([`BertModel`] のようなもの)で、もう1つは画像分類に適したモデル([`BertForSequenceClassification`] のようなもの)です。
+
+前述したように、この例をシンプルに保つために、モデルの緩いラッパーのみを書きます。このクラスを書く前に行う必要がある唯一のことは、ブロックタイプと実際のブロッククラスの間のマップです。その後、すべてを `ResNet` クラスに渡して設定からモデルを定義します:
+
+```py
+from transformers import PreTrainedModel
+from timm.models.resnet import BasicBlock, Bottleneck, ResNet
+from .configuration_resnet import ResnetConfig
+
+
+BLOCK_MAPPING = {"basic": BasicBlock, "bottleneck": Bottleneck}
+
+
+class ResnetModel(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor):
+ return self.model.forward_features(tensor)
+```
+
+画像を分類するモデルの場合、forwardメソッドを変更するだけです:
+
+```py
+import torch
+
+
+class ResnetModelForImageClassification(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor, labels=None):
+ logits = self.model(tensor)
+ if labels is not None:
+ loss = torch.nn.functional.cross_entropy(logits, labels)
+ return {"loss": loss, "logits": logits}
+ return {"logits": logits}
+```
+
+両方の場合、`PreTrainedModel`から継承し、`config`を使用してスーパークラスの初期化を呼び出します(通常の`torch.nn.Module`を書くときのような感じです)。
+`config_class`を設定する行は必須ではありませんが、(最後のセクションを参照)、モデルを自動クラスに登録したい場合に使用できます。
+
+
+
+モデルがライブラリ内のモデルと非常に似ている場合、このモデルと同じ構成を再利用できます。
+
+
+
+モデルが返す内容は何でも構いませんが、ラベルが渡されるときに損失を含む辞書を返す(`ResnetModelForImageClassification`のように行ったもの)と、
+モデルを[`Trainer`]クラス内で直接使用できるようになります。独自のトレーニングループまたは他のライブラリを使用する予定である限り、
+別の出力形式を使用することも問題ありません。
+
+さて、モデルクラスができたので、1つ作成しましょう:
+
+```py
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+```
+
+再度、[`PreTrainedModel`]のいずれかのメソッド、例えば[`~PreTrainedModel.save_pretrained`]や
+[`~PreTrainedModel.push_to_hub`]などを使用できます。次のセクションでは、モデルの重みをコードと一緒に
+Hugging Face Hub にプッシュする方法を見てみます。
+しかし、まずはモデル内に事前学習済みの重みをロードしましょう。
+
+独自のユースケースでは、おそらく独自のデータでカスタムモデルをトレーニングすることになるでしょう。
+このチュートリアルではスピードアップのために、resnet50dの事前学習済みバージョンを使用します。
+私たちのモデルはそれをラップするだけなので、これらの重みを転送するのは簡単です:
+
+
+```py
+import timm
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+さて、[`~PreTrainedModel.save_pretrained`]または[`~PreTrainedModel.push_to_hub`]を実行したときに、
+モデルのコードが保存されるようにする方法を見てみましょう。
+
+## Sending the code to the Hub
+
+
+
+このAPIは実験的であり、次のリリースでわずかな変更があるかもしれません。
+
+
+
+まず、モデルが`.py`ファイルに完全に定義されていることを確認してください。
+ファイルは相対インポートを他のファイルに依存できますが、すべてのファイルが同じディレクトリにある限り(まだこの機能ではサブモジュールはサポートしていません)、問題ありません。
+この例では、現在の作業ディレクトリ内に名前が「resnet_model」のフォルダを作成し、その中に`modeling_resnet.py`ファイルと`configuration_resnet.py`ファイルを定義します。
+構成ファイルには`ResnetConfig`のコードが含まれ、モデリングファイルには`ResnetModel`と`ResnetModelForImageClassification`のコードが含まれています。
+
+
+```
+.
+└── resnet_model
+ ├── __init__.py
+ ├── configuration_resnet.py
+ └── modeling_resnet.py
+```
+
+`__init__.py`は空であっても問題ありません。Pythonが`resnet_model`をモジュールとして検出できるようにするために存在します。
+
+
+
+ライブラリからモデリングファイルをコピーする場合、ファイルの先頭にあるすべての相対インポートを`transformers`パッケージからインポートに置き換える必要があります。
+
+
+
+既存の設定やモデルを再利用(またはサブクラス化)できることに注意してください。
+
+コミュニティとモデルを共有するために、次の手順に従ってください:まず、新しく作成したファイルからResNetモデルと設定をインポートします:
+
+
+```py
+from resnet_model.configuration_resnet import ResnetConfig
+from resnet_model.modeling_resnet import ResnetModel, ResnetModelForImageClassification
+```
+
+次に、`save_pretrained`メソッドを使用してこれらのオブジェクトのコードファイルをコピーし、特定のAutoクラス(特にモデルの場合)に正しく登録するようライブラリに指示する必要があります。次のように実行します:
+
+```py
+ResnetConfig.register_for_auto_class()
+ResnetModel.register_for_auto_class("AutoModel")
+ResnetModelForImageClassification.register_for_auto_class("AutoModelForImageClassification")
+```
+
+注意: 設定については自動クラスを指定する必要はありません(設定用の自動クラスは1つしかなく、[`AutoConfig`]です)が、
+モデルについては異なります。カスタムモデルは多くの異なるタスクに適している可能性があるため、
+モデルが正確な自動クラスのうちどれに適しているかを指定する必要があります。
+
+次に、前述のように設定とモデルを作成しましょう:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+モデルをHubに送信するには、ログインしていることを確認してください。ターミナルで次のコマンドを実行します:
+
+```bash
+huggingface-cli login
+```
+
+またはノートブックから:
+
+```py
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+次に、次のようにして、独自の名前空間にプッシュできます(または、メンバーである組織にプッシュできます):
+
+```py
+resnet50d.push_to_hub("custom-resnet50d")
+```
+
+モデリングの重みとJSON形式の構成に加えて、このフォルダー「custom-resnet50d」内のモデリングおよび構成「.py」ファイルもコピーされ、結果はHubにアップロードされました。結果はこの[model repo](https://huggingface.co/sgugger/custom-resnet50d)で確認できます。
+
+詳細については、[Hubへのプッシュ方法](model_sharing)を参照してください。
+
+## Using a model with custom code
+
+自動クラスと `from_pretrained` メソッドを使用して、リポジトリ内のカスタムコードファイルと共に任意の構成、モデル、またはトークナイザを使用できます。 Hubにアップロードされるすべてのファイルとコードはマルウェアのスキャンが実施されます(詳細は[Hubセキュリティ](https://huggingface.co/docs/hub/security#malware-scanning)ドキュメンテーションを参照してください)、しかし、依然として悪意のあるコードを実行しないために、モデルコードと作者を確認する必要があります。
+`trust_remote_code=True` を設定してカスタムコードを持つモデルを使用できます:
+
+
+```py
+from transformers import AutoModelForImageClassification
+
+model = AutoModelForImageClassification.from_pretrained("sgugger/custom-resnet50d", trust_remote_code=True)
+```
+
+コミットハッシュを「revision」として渡すことも強く推奨されています。これにより、モデルの作者がコードを悪意のある新しい行で更新しなかったことを確認できます(モデルの作者を完全に信頼している場合を除きます)。
+
+
+```py
+commit_hash = "ed94a7c6247d8aedce4647f00f20de6875b5b292"
+model = AutoModelForImageClassification.from_pretrained(
+ "sgugger/custom-resnet50d", trust_remote_code=True, revision=commit_hash
+)
+```
+
+モデルリポジトリのコミット履歴をブラウジングする際には、任意のコミットのコミットハッシュを簡単にコピーできるボタンがあります。
+
+## Registering a model with custom code to the auto classes
+
+🤗 Transformersを拡張するライブラリを作成している場合、独自のモデルを含めるために自動クラスを拡張したい場合があります。
+これはコードをHubにプッシュすることとは異なり、ユーザーはカスタムモデルを取得するためにあなたのライブラリをインポートする必要があります
+(Hubからモデルコードを自動的にダウンロードするのとは対照的です)。
+
+構成に既存のモデルタイプと異なる `model_type` 属性がある限り、またあなたのモデルクラスが適切な `config_class` 属性を持っている限り、
+次のようにそれらを自動クラスに追加できます:
+
+```py
+from transformers import AutoConfig, AutoModel, AutoModelForImageClassification
+
+AutoConfig.register("resnet", ResnetConfig)
+AutoModel.register(ResnetConfig, ResnetModel)
+AutoModelForImageClassification.register(ResnetConfig, ResnetModelForImageClassification)
+```
+
+注意: `AutoConfig` にカスタム設定を登録する際の最初の引数は、カスタム設定の `model_type` と一致する必要があります。
+また、任意の自動モデルクラスにカスタムモデルを登録する際の最初の引数は、それらのモデルの `config_class` と一致する必要があります。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/custom_tools.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/custom_tools.md
new file mode 100644
index 0000000000000000000000000000000000000000..4a9926ba2c2204ee27dd6669c47d34551573cbbb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/custom_tools.md
@@ -0,0 +1,26 @@
+
+
+# Custom Tools and Prompts
+
+
+
+The Agents framework has significantly changed in version v4.41.0.
+This document has been removed as it was referencing an older API.
+
+We eagerly welcome new contributions for the updated API.
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/fast_tokenizers.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/fast_tokenizers.md
new file mode 100644
index 0000000000000000000000000000000000000000..d97e59ed0ed25344e26508f868b1dbe317437242
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/fast_tokenizers.md
@@ -0,0 +1,73 @@
+
+
+# Use tokenizers from 🤗 Tokenizers
+
+[`PreTrainedTokenizerFast`]は[🤗 Tokenizers](https://huggingface.co/docs/tokenizers)ライブラリに依存しています。🤗 Tokenizersライブラリから取得したトークナイザーは、非常に簡単に🤗 Transformersにロードできます。
+
+具体的な内容に入る前に、まずはいくつかの行でダミーのトークナイザーを作成することから始めましょう:
+
+
+```python
+>>> from tokenizers import Tokenizer
+>>> from tokenizers.models import BPE
+>>> from tokenizers.trainers import BpeTrainer
+>>> from tokenizers.pre_tokenizers import Whitespace
+
+>>> tokenizer = Tokenizer(BPE(unk_token="[UNK]"))
+>>> trainer = BpeTrainer(special_tokens=["[UNK]", "[CLS]", "[SEP]", "[PAD]", "[MASK]"])
+
+>>> tokenizer.pre_tokenizer = Whitespace()
+>>> files = [...]
+>>> tokenizer.train(files, trainer)
+```
+
+私たちは今、定義したファイルにトレーニングされたトークナイザーを持っています。これをランタイムで引き続き使用するか、
+将来の再利用のためにJSONファイルに保存することができます。
+
+## Loading directly from the tokenizer object
+
+🤗 Transformersライブラリでこのトークナイザーオブジェクトをどのように活用できるかを見てみましょう。[`PreTrainedTokenizerFast`]クラスは、
+*tokenizer*オブジェクトを引数として受け入れ、簡単にインスタンス化できるようにします。
+
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_object=tokenizer)
+```
+
+このオブジェクトは、🤗 Transformers トークナイザーが共有するすべてのメソッドと一緒に使用できます!詳細については、[トークナイザーページ](main_classes/tokenizer)をご覧ください。
+
+## Loading from a JSON file
+
+JSONファイルからトークナイザーを読み込むには、まずトークナイザーを保存することから始めましょう:
+
+```python
+>>> tokenizer.save("tokenizer.json")
+```
+
+このファイルを保存したパスは、`PreTrainedTokenizerFast` の初期化メソッドに `tokenizer_file` パラメータを使用して渡すことができます:
+
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_file="tokenizer.json")
+```
+
+このオブジェクトは、🤗 Transformers トークナイザーが共有するすべてのメソッドと一緒に使用できるようになりました!詳細については、[トークナイザーページ](main_classes/tokenizer)をご覧ください。
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/generation_strategies.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/generation_strategies.md
new file mode 100644
index 0000000000000000000000000000000000000000..ff71d0c9b15d1019fbfca0420d7322992049efd5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/generation_strategies.md
@@ -0,0 +1,345 @@
+
+
+# Text generation strategies
+
+テキスト生成は、オープンエンドのテキスト生成、要約、翻訳など、多くの自然言語処理タスクに不可欠です。また、テキストを出力とするさまざまな混在モダリティアプリケーションにも影響を与えており、例えば音声からテキストへの変換や画像からテキストへの変換などがあります。テキストを生成できるいくつかのモデルには、GPT2、XLNet、OpenAI GPT、CTRL、TransformerXL、XLM、Bart、T5、GIT、Whisperが含まれます。
+
+[`~generation.GenerationMixin.generate`] メソッドを使用して、異なるタスクのテキスト出力を生成するいくつかの例をご紹介します:
+* [テキスト要約](./tasks/summarization#inference)
+* [画像のキャプション](./model_doc/git#transformers.GitForCausalLM.forward.example)
+* [音声の転記](./model_doc/whisper#transformers.WhisperForConditionalGeneration.forward.example)
+
+generateメソッドへの入力は、モデルのモダリティに依存します。これらの入力は、AutoTokenizerやAutoProcessorなどのモデルのプリプロセッサクラスによって返されます。モデルのプリプロセッサが複数の種類の入力を生成する場合は、すべての入力をgenerate()に渡します。各モデルのプリプロセッサについての詳細は、対応するモデルのドキュメンテーションで確認できます。
+
+テキストを生成するためのトークンの選択プロセスはデコーディングとして知られ、`generate()`メソッドが使用するデコーディング戦略をカスタマイズできます。デコーディング戦略を変更することは、訓練可能なパラメータの値を変更しませんが、生成されるテキストの品質に顕著な影響を与えることがあります。これにより、テキスト内の繰り返しを減少させ、より一貫性のあるテキストを生成するのに役立ちます。
+
+このガイドでは以下の内容が説明されています:
+* デフォルトのテキスト生成設定
+* 一般的なデコーディング戦略とその主要なパラメータ
+* 🤗 Hubのあなたのファインチューンモデルとカスタム生成設定の保存と共有
+
+## Default text generation configuration
+
+モデルのデコーディング戦略は、その生成設定で定義されています。[`pipeline`] 内で推論に事前訓練モデルを使用する際には、モデルはデフォルトの生成設定を内部で適用する `PreTrainedModel.generate()` メソッドを呼び出します。デフォルトの設定は、モデルにカスタム設定が保存されていない場合にも使用されます。
+
+モデルを明示的に読み込む場合、それに付属する生成設定を `model.generation_config` を介して確認できます。
+
+```python
+>>> from transformers import AutoModelForCausalLM
+
+>>> model = AutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+>>> model.generation_config
+GenerationConfig {
+ "bos_token_id": 50256,
+ "eos_token_id": 50256,
+}
+```
+
+`model.generation_config` を出力すると、デフォルトの生成設定から異なる値のみが表示され、デフォルトの値はリストされません。
+
+デフォルトの生成設定では、出力のサイズは入力プロンプトとの組み合わせで最大20トークンに制限されており、リソース制限に達しないようにしています。デフォルトのデコーディング戦略は貪欲探索で、最も確率の高いトークンを次のトークンとして選択する最も単純なデコーディング戦略です。多くのタスクや小さな出力サイズの場合、これはうまく機能します。ただし、長い出力を生成するために使用される場合、貪欲探索は高度に繰り返される結果を生成し始めることがあります。
+
+## Customize text generation
+
+`generate` メソッドに直接パラメータとその値を渡すことで、`generation_config` を上書きできます。
+
+```python
+>>> my_model.generate(**inputs, num_beams=4, do_sample=True) # doctest: +SKIP
+```
+
+デフォルトのデコーディング戦略がほとんどのタスクでうまく機能する場合でも、いくつかの設定を微調整できます。一般的に調整されるパラメータには次のものがあります:
+
+- `max_new_tokens`: 生成するトークンの最大数。つまり、出力シーケンスのサイズであり、プロンプト内のトークンは含まれません。
+- `num_beams`: 1よりも大きなビーム数を指定することで、貪欲検索からビームサーチに切り替えることができます。この戦略では、各時間ステップでいくつかの仮説を評価し、最終的に全体のシーケンスに対する最も高い確率を持つ仮説を選択します。これにより、初期の確率が低いトークンで始まる高確率のシーケンスが貪欲検索によって無視されることがなくなります。
+- `do_sample`: このパラメータを`True`に設定すると、多項分布サンプリング、ビームサーチ多項分布サンプリング、Top-Kサンプリング、Top-pサンプリングなどのデコーディング戦略が有効になります。これらの戦略は、各戦略固有の調整を含む単語彙全体の確率分布から次のトークンを選択します。
+- `num_return_sequences`: 各入力に対して返すシーケンス候補の数。これは、複数のシーケンス候補をサポートするデコーディング戦略(ビームサーチやサンプリングのバリエーションなど)にのみ適用されます。貪欲検索や対照的な検索など、単一の出力シーケンスを返すデコーディング戦略では使用できません。
+
+## Save a custom decoding strategy with your model
+
+特定の生成構成で調整したモデルを共有したい場合、以下の手順を実行できます:
+* [`GenerationConfig`] クラスのインスタンスを作成する
+* デコーディング戦略のパラメータを指定する
+* [`GenerationConfig.save_pretrained`] を使用して生成構成を保存し、`config_file_name` 引数を空にすることを忘れないでください
+* `push_to_hub` を `True` に設定して、構成をモデルのリポジトリにアップロードします
+
+```python
+>>> from transformers import AutoModelForCausalLM, GenerationConfig
+
+>>> model = AutoModelForCausalLM.from_pretrained("my_account/my_model") # doctest: +SKIP
+>>> generation_config = GenerationConfig(
+... max_new_tokens=50, do_sample=True, top_k=50, eos_token_id=model.config.eos_token_id
+... )
+>>> generation_config.save_pretrained("my_account/my_model", push_to_hub=True) # doctest: +SKIP
+```
+
+1つのディレクトリに複数の生成設定を保存することもでき、[`GenerationConfig.save_pretrained`] の `config_file_name`
+引数を使用します。後で [`GenerationConfig.from_pretrained`] でこれらをインスタンス化できます。これは、1つのモデルに対して複数の生成設定を保存したい場合に便利です
+(例:サンプリングを使用したクリエイティブなテキスト生成用の1つと、ビームサーチを使用した要約用の1つ)。モデルに設定ファイルを追加するには、適切な Hub 権限が必要です。
+
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer, GenerationConfig
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("google-t5/t5-small")
+
+>>> translation_generation_config = GenerationConfig(
+... num_beams=4,
+... early_stopping=True,
+... decoder_start_token_id=0,
+... eos_token_id=model.config.eos_token_id,
+... pad_token=model.config.pad_token_id,
+... )
+
+>>> # Tip: add `push_to_hub=True` to push to the Hub
+>>> translation_generation_config.save_pretrained("/tmp", "translation_generation_config.json")
+
+>>> # You could then use the named generation config file to parameterize generation
+>>> generation_config = GenerationConfig.from_pretrained("/tmp", "translation_generation_config.json")
+>>> inputs = tokenizer("translate English to French: Configuration files are easy to use!", return_tensors="pt")
+>>> outputs = model.generate(**inputs, generation_config=generation_config)
+>>> print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['Les fichiers de configuration sont faciles à utiliser!']
+```
+
+## Streaming
+
+`generate()` は、その `streamer` 入力を介してストリーミングをサポートしています。`streamer` 入力は、次のメソッドを持つクラスのインスタンスと互換性があります:`put()` と `end()`。内部的には、`put()` は新しいトークンをプッシュするために使用され、`end()` はテキスト生成の終了をフラグ付けするために使用されます。
+
+
+
+ストリーマークラスのAPIはまだ開発中であり、将来変更される可能性があります。
+
+
+
+実際には、さまざまな目的に対して独自のストリーミングクラスを作成できます!また、使用できる基本的なストリーミングクラスも用意されています。例えば、[`TextStreamer`] クラスを使用して、`generate()` の出力を画面に単語ごとにストリームすることができます:
+
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, TextStreamer
+
+>>> tok = AutoTokenizer.from_pretrained("openai-community/gpt2")
+>>> model = AutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+>>> inputs = tok(["An increasing sequence: one,"], return_tensors="pt")
+>>> streamer = TextStreamer(tok)
+
+>>> # Despite returning the usual output, the streamer will also print the generated text to stdout.
+>>> _ = model.generate(**inputs, streamer=streamer, max_new_tokens=20)
+An increasing sequence: one, two, three, four, five, six, seven, eight, nine, ten, eleven,
+```
+
+## Decoding strategies
+
+特定の `generate()` パラメータの組み合わせ、そして最終的に `generation_config` は、特定のデコーディング戦略を有効にするために使用できます。このコンセプトが新しい場合、[このブログポスト](https://huggingface.co/blog/how-to-generate)を読むことをお勧めします。このブログポストでは、一般的なデコーディング戦略がどのように動作するかが説明されています。
+
+ここでは、デコーディング戦略を制御するいくつかのパラメータを示し、それらをどのように使用できるかを説明します。
+
+### Greedy Search
+
+[`generate`] はデフォルトで貪欲探索デコーディングを使用するため、有効にするためにパラメータを渡す必要はありません。これは、パラメータ `num_beams` が 1 に設定され、`do_sample=False` であることを意味します。
+
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> prompt = "I look forward to"
+>>> checkpoint = "distilbert/distilgpt2"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+>>> outputs = model.generate(**inputs)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['I look forward to seeing you all again!\n\n\n\n\n\n\n\n\n\n\n']
+```
+
+### Contrastive search
+
+コントラスティブ検索デコーディング戦略は、2022年の論文[A Contrastive Framework for Neural Text Generation](https://arxiv.org/abs/2202.06417)で提案されました。
+これは、非反復的でありながら一貫性のある長い出力を生成するために優れた結果を示しています。コントラスティブ検索の動作原理を学ぶには、[このブログポスト](https://huggingface.co/blog/introducing-csearch)をご覧ください。
+コントラスティブ検索の動作を有効にし、制御する2つの主要なパラメータは「penalty_alpha」と「top_k」です:
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForCausalLM
+
+>>> checkpoint = "openai-community/gpt2-large"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+
+>>> prompt = "Hugging Face Company is"
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> outputs = model.generate(**inputs, penalty_alpha=0.6, top_k=4, max_new_tokens=100)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Hugging Face Company is a family owned and operated business. We pride ourselves on being the best
+in the business and our customer service is second to none.\n\nIf you have any questions about our
+products or services, feel free to contact us at any time. We look forward to hearing from you!']
+```
+
+### Multinomial sampling
+
+常に最高確率のトークンを次のトークンとして選択する貪欲検索とは異なり、多項分布サンプリング(または祖先サンプリングとも呼ばれます)はモデルによって提供される語彙全体の確率分布に基づいて次のトークンをランダムに選択します。ゼロ以外の確率を持つすべてのトークンには選択される可能性があり、これにより繰り返しのリスクが減少します。
+
+多項分布サンプリングを有効にするには、`do_sample=True` および `num_beams=1` を設定します。
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForCausalLM, set_seed
+>>> set_seed(0) # For reproducibility
+
+>>> checkpoint = "openai-community/gpt2-large"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+
+>>> prompt = "Today was an amazing day because"
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> outputs = model.generate(**inputs, do_sample=True, num_beams=1, max_new_tokens=100)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Today was an amazing day because when you go to the World Cup and you don\'t, or when you don\'t get invited,
+that\'s a terrible feeling."']
+```
+
+### Beam-search decoding
+
+貪欲探索とは異なり、ビームサーチデコーディングは各時間ステップでいくつかの仮説を保持し、最終的にシーケンス全体で最も確率が高い仮説を選択します。これにより、貪欲探索では無視されてしまう初期トークンの確率が低い高確率のシーケンスを特定する利点があります。
+
+このデコーディング戦略を有効にするには、`num_beams`(追跡する仮説の数)を1よりも大きな値に指定します。
+
+希望されるテキストの翻訳がお手伝いできて嬉しいです!もしさらなる質問やサポートが必要な場合は、お気軽にお知らせください。
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> prompt = "It is astonishing how one can"
+>>> checkpoint = "openai-community/gpt2-medium"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+
+>>> outputs = model.generate(**inputs, num_beams=5, max_new_tokens=50)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['It is astonishing how one can have such a profound impact on the lives of so many people in such a short period of
+time."\n\nHe added: "I am very proud of the work I have been able to do in the last few years.\n\n"I have']
+```
+
+### Beam-search multinomial sampling
+
+その名前からもわかるように、このデコーディング戦略はビームサーチと多項サンプリングを組み合わせています。このデコーディング戦略を使用するには、`num_beams` を1より大きな値に設定し、`do_sample=True` を設定する必要があります。
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM, set_seed
+>>> set_seed(0) # For reproducibility
+
+>>> prompt = "translate English to German: The house is wonderful."
+>>> checkpoint = "google-t5/t5-small"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+
+>>> outputs = model.generate(**inputs, num_beams=5, do_sample=True)
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'Das Haus ist wunderbar.'
+```
+
+### Diverse beam search decoding
+
+多様なビームサーチデコーディング戦略は、ビームサーチ戦略の拡張であり、選択肢からより多様なビームシーケンスを生成できるようにします。この仕組みの詳細については、[Diverse Beam Search: Decoding Diverse Solutions from Neural Sequence Models](https://arxiv.org/pdf/1610.02424.pdf) をご参照ください。このアプローチには、`num_beams`、`num_beam_groups`、および `diversity_penalty` という3つの主要なパラメータがあります。多様性ペナルティは、出力がグループごとに異なることを保証し、ビームサーチは各グループ内で使用されます。
+
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+>>> checkpoint = "google/pegasus-xsum"
+>>> prompt = (
+... "The Permaculture Design Principles are a set of universal design principles "
+... "that can be applied to any location, climate and culture, and they allow us to design "
+... "the most efficient and sustainable human habitation and food production systems. "
+... "Permaculture is a design system that encompasses a wide variety of disciplines, such "
+... "as ecology, landscape design, environmental science and energy conservation, and the "
+... "Permaculture design principles are drawn from these various disciplines. Each individual "
+... "design principle itself embodies a complete conceptual framework based on sound "
+... "scientific principles. When we bring all these separate principles together, we can "
+... "create a design system that both looks at whole systems, the parts that these systems "
+... "consist of, and how those parts interact with each other to create a complex, dynamic, "
+... "living system. Each design principle serves as a tool that allows us to integrate all "
+... "the separate parts of a design, referred to as elements, into a functional, synergistic, "
+... "whole system, where the elements harmoniously interact and work together in the most "
+... "efficient way possible."
+... )
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+
+>>> outputs = model.generate(**inputs, num_beams=5, num_beam_groups=5, max_new_tokens=30, diversity_penalty=1.0)
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'The Design Principles are a set of universal design principles that can be applied to any location, climate and
+culture, and they allow us to design the'
+```
+
+### Assisted Decoding
+
+アシストデコーディングは、上記のデコーディング戦略を変更したもので、同じトークナイザー(理想的にははるかに小さなモデル)を使用して、いくつかの候補トークンを貪欲に生成するアシスタントモデルを使用します。その後、主要なモデルは候補トークンを1つの前向きパスで検証し、デコーディングプロセスを高速化します。現在、アシストデコーディングでは貪欲検索とサンプリングのみがサポートされており、バッチ入力はサポートされていません。アシストデコーディングの詳細については、[このブログ記事](https://huggingface.co/blog/assisted-generation) をご覧ください。
+
+アシストデコーディングを有効にするには、`assistant_model` 引数をモデルで設定します。
+
+このガイドは、さまざまなデコーディング戦略を可能にする主要なパラメーターを説明しています。さらに高度なパラメーターは [`generate`] メソッドに存在し、[`generate`] メソッドの動作をさらに制御できます。使用可能なパラメーターの完全なリストについては、[APIドキュメント](./main_classes/text_generation.md) を参照してください。
+
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> prompt = "Alice and Bob"
+>>> checkpoint = "EleutherAI/pythia-1.4b-deduped"
+>>> assistant_checkpoint = "EleutherAI/pythia-160m-deduped"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+>>> assistant_model = AutoModelForCausalLM.from_pretrained(assistant_checkpoint)
+>>> outputs = model.generate(**inputs, assistant_model=assistant_model)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Alice and Bob are sitting in a bar. Alice is drinking a beer and Bob is drinking a']
+```
+
+サンプリング方法を使用する場合、アシストデコーディングでは `temperature` 引数を使用して、多項サンプリングと同様にランダム性を制御できます。ただし、アシストデコーディングでは、温度を低くすることで遅延の改善に役立ちます。
+
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, set_seed
+>>> set_seed(42) # For reproducibility
+
+>>> prompt = "Alice and Bob"
+>>> checkpoint = "EleutherAI/pythia-1.4b-deduped"
+>>> assistant_checkpoint = "EleutherAI/pythia-160m-deduped"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+>>> assistant_model = AutoModelForCausalLM.from_pretrained(assistant_checkpoint)
+>>> outputs = model.generate(**inputs, assistant_model=assistant_model, do_sample=True, temperature=0.5)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Alice and Bob are going to the same party. It is a small party, in a small']
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/glossary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/glossary.md
new file mode 100644
index 0000000000000000000000000000000000000000..39148f5d0f48c1a6db1e5cd6b5dd4a6aa2b2ce3f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/glossary.md
@@ -0,0 +1,444 @@
+
+
+# Glossary
+
+この用語集は、一般的な機械学習と 🤗 トランスフォーマーの用語を定義し、ドキュメンテーションをより理解するのに役立ちます。
+
+## A
+
+### attention mask
+
+アテンション マスクは、シーケンスをバッチ処理する際に使用されるオプションの引数です。
+
+
+
+各モデルのラベルは異なる場合があるため、常に各モデルのドキュメントを確認して、それらの特定のラベルに関する詳細情報を確認してください!
+
+
+
+ベースモデル([`BertModel`])はラベルを受け入れません。これらはベースのトランスフォーマーモデルであり、単に特徴を出力します。
+
+
+### large language models (LLM)
+
+大量のデータでトレーニングされた変換器言語モデル(GPT-3、BLOOM、OPT)を指す一般的な用語です。これらのモデルは通常、多くの学習可能なパラメータを持っています(たとえば、GPT-3の場合、1750億個)。
+
+## M
+
+### masked language modeling (MLM)
+
+モデルはテキストの破損バージョンを見る事前トレーニングタスクで、通常はランダムに一部のトークンをマスキングして元のテキストを予測する必要があります。
+
+### multimodal
+
+テキストと別の種類の入力(たとえば画像)を組み合わせるタスクです。
+
+## N
+
+### Natural language generation (NLG)
+
+テキストを生成する関連するすべてのタスク(たとえば、[Transformersで書く](https://transformer.huggingface.co/)、翻訳など)。
+
+### Natural language processing (NLP)
+
+テキストを扱う方法を一般的に表現したものです。
+
+### Natural language understanding (NLU)
+
+テキスト内に何があるかを理解する関連するすべてのタスク(たとえば、テキスト全体の分類、個々の単語の分類など)。
+
+## P
+
+### pipeline
+
+🤗 Transformersのパイプラインは、データの前処理と変換を特定の順序で実行してデータを処理し、モデルから予測を返す一連のステップを指す抽象化です。パイプラインに見られるいくつかのステージの例には、データの前処理、特徴抽出、正規化などがあります。
+
+詳細については、[推論のためのパイプライン](https://huggingface.co/docs/transformers/pipeline_tutorial)を参照してください。
+
+### pixel values
+
+モデルに渡される画像の数値表現のテンソルです。ピクセル値は、形状が [`バッチサイズ`, `チャネル数`, `高さ`, `幅`] の行列で、画像プロセッサから生成されます。
+
+### pooling
+
+行列を小さな行列に縮小する操作で、プール対象の次元の最大値または平均値を取ることが一般的です。プーリングレイヤーは一般的に畳み込みレイヤーの間に見られ、特徴表現をダウンサンプリングします。
+
+### position IDs
+
+トークンごとの位置が埋め込まれているRNNとは異なり、トランスフォーマーは各トークンの位置を把握していません。したがって、モデルはトークンの位置を識別するために位置ID(`position_ids`)を使用します。
+
+これはオプションのパラメータです。モデルに `position_ids` が渡されない場合、IDは自動的に絶対的な位置埋め込みとして作成されます。
+
+絶対的な位置埋め込みは範囲 `[0、config.max_position_embeddings - 1]` から選択されます。一部のモデルは、正弦波位置埋め込みや相対位置埋め込みなど、他のタイプの位置埋め込みを使用することがあります。
+
+
+### preprocessing
+
+生データを機械学習モデルで簡単に処理できる形式に準備するタスクです。例えば、テキストは通常、トークン化によって前処理されます。他の入力タイプに対する前処理の具体的な方法を知りたい場合は、[Preprocess](https://huggingface.co/docs/transformers/preprocessing) チュートリアルをご覧ください。
+
+### pretrained model
+
+あるデータ(たとえば、Wikipedia全体など)で事前に学習されたモデルです。事前学習の方法には、自己教師ありの目的が含まれ、テキストを読み取り、次の単語を予測しようとするもの([因果言語モデリング](#causal-language-modeling)を参照)や、一部の単語をマスクし、それらを予測しようとするもの([マスク言語モデリング](#masked-language-modeling-mlm)を参照)があります。
+
+音声とビジョンモデルには独自の事前学習の目的があります。たとえば、Wav2Vec2は音声モデルで、モデルに対して「真の」音声表現を偽の音声表現のセットから識別する必要がある対比的なタスクで事前学習されています。一方、BEiTはビジョンモデルで、一部の画像パッチをマスクし、モデルにマスクされたパッチを予測させるタスク(マスク言語モデリングの目的と似ています)で事前学習されています。
+
+## R
+
+### recurrent neural network (RNN)
+
+テキストを処理するために層をループさせるモデルの一種です。
+
+### representation learning
+
+生データの意味のある表現を学習する機械学習のサブフィールドです。表現学習の技術の一部には単語埋め込み、オートエンコーダー、Generative Adversarial Networks(GANs)などがあります。
+
+## S
+
+### sampling rate
+
+秒ごとに取られるサンプル(オーディオ信号など)の数をヘルツ単位で測定したものです。サンプリングレートは音声などの連続信号を離散化する結果です。
+
+### self-attention
+
+入力の各要素は、どの他の要素に注意を払うべきかを検出します。
+
+### self-supervised learning
+
+モデルがラベルのないデータから自分自身の学習目標を作成する機械学習技術のカテゴリです。これは[教師なし学習](#unsupervised-learning)や[教師あり学習](#supervised-learning)とは異なり、学習プロセスはユーザーからは明示的には監督されていない点が異なります。
+
+自己教師あり学習の1つの例は[マスク言語モデリング](#masked-language-modeling-mlm)で、モデルには一部のトークンが削除された文が与えられ、欠落したトークンを予測するように学習します。
+
+### semi-supervised learning
+
+ラベル付きデータの少量とラベルのないデータの大量を組み合わせてモデルの精度を向上させる広範な機械学習トレーニング技術のカテゴリです。[教師あり学習](#supervised-learning)や[教師なし学習](#unsupervised-learning)とは異なり、半教師あり学習のアプローチの1つは「セルフトレーニング」であり、モデルはラベル付きデータでトレーニングされ、次にラベルのないデータで予測を行います。モデルが最も自信を持って予測する部分がラベル付きデータセットに追加され、モデルの再トレーニングに使用されます。
+
+### sequence-to-sequence (seq2seq)
+
+入力から新しいシーケンスを生成するモデルです。翻訳モデルや要約モデル([Bart](model_doc/bart)や[T5](model_doc/t5)など)などがこれに該当します。
+
+### stride
+
+[畳み込み](#convolution)または[プーリング](#pooling)において、ストライドはカーネルが行列上で移動する距離を指します。ストライドが1の場合、カーネルは1ピクセルずつ移動し、ストライドが2の場合、カーネルは2ピクセルずつ移動します。
+
+### supervised learning
+
+モデルのトレーニング方法の一つで、直接ラベル付きデータを使用してモデルの性能を修正し指導します。データがトレーニングされているモデルに供給され、その予測が既知のラベルと比較されます。モデルは予測がどれだけ誤っていたかに基づいて重みを更新し、プロセスはモデルの性能を最適化するために繰り返されます。
+
+## T
+
+### token
+
+文の一部であり、通常は単語ですが、サブワード(一般的でない単語はしばしばサブワードに分割されることがあります)または句読点の記号であることもあります。
+
+### token Type IDs
+
+一部のモデルは、文のペアの分類や質問応答を行うことを目的としています。
+
+
+
+
+## 目次
+
+ドキュメントは以下の5つのセクションで構成されています:
+
+- **はじめに** は、ライブラリのクイックツアーとライブラリを使い始めるためのインストール手順を提供しています。
+- **チュートリアル** は、初心者が始めるのに最適な場所です。このセクションでは、ライブラリを使い始めるために必要な基本的なスキルを習得できます。
+- **HOW-TOガイド** は、言語モデリングのために学習済みモデルをfinetuningすることやカスタムモデルの作成と共有の方法などといった特定の目標を達成するための方法を示しています。
+- **コンセプトガイド** は、モデルやタスク、そして 🤗 Transformersの設計思想の背景にある基本的にコンセプトや考え方についてより深く考察し解説しています。
+- **API** 全てのクラスと関数を説明します:
+
+ - **MAIN CLASSES** は、configuration, model, tokenizer, pipelineといった最も重要なクラスについて詳細に説明しています。
+ - **MODELS** は、ライブラリで実装されているそれぞれのモデルに関連したクラスと関数を詳細に説明しています。
+ - **INTERNAL HELPERS** は、内部で使用されているユーティリティクラスや関数を詳細に説明しています。
+
+### サポートされているモデル
+
+
+
+1. **[ALBERT](https://huggingface.co/docs/transformers/model_doc/albert)** (Google Research and the Toyota Technological Institute at Chicago から) Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut から公開された研究論文: [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942)
+1. **[AltCLIP](https://huggingface.co/docs/transformers/main/model_doc/altclip)** (BAAI から) Chen, Zhongzhi and Liu, Guang and Zhang, Bo-Wen and Ye, Fulong and Yang, Qinghong and Wu, Ledell から公開された研究論文: [AltCLIP: Altering the Language Encoder in CLIP for Extended Language Capabilities](https://arxiv.org/abs/2211.06679)
+1. **[Audio Spectrogram Transformer](https://huggingface.co/docs/transformers/model_doc/audio-spectrogram-transformer)** (MIT から) Yuan Gong, Yu-An Chung, James Glass から公開された研究論文: [AST: Audio Spectrogram Transformer](https://arxiv.org/abs/2104.01778)
+1. **[BART](https://huggingface.co/docs/transformers/model_doc/bart)** (Facebook から) Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer から公開された研究論文: [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461)
+1. **[BARThez](https://huggingface.co/docs/transformers/model_doc/barthez)** (École polytechnique から) Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis から公開された研究論文: [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321)
+1. **[BARTpho](https://huggingface.co/docs/transformers/model_doc/bartpho)** (VinAI Research から) Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen から公開された研究論文: [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701)
+1. **[BEiT](https://huggingface.co/docs/transformers/model_doc/beit)** (Microsoft から) Hangbo Bao, Li Dong, Furu Wei から公開された研究論文: [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254)
+1. **[BERT](https://huggingface.co/docs/transformers/model_doc/bert)** (Google から) Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova から公開された研究論文: [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805)
+1. **[BERT For Sequence Generation](https://huggingface.co/docs/transformers/model_doc/bert-generation)** (Google から) Sascha Rothe, Shashi Narayan, Aliaksei Severyn から公開された研究論文: [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461)
+1. **[BERTweet](https://huggingface.co/docs/transformers/model_doc/bertweet)** (VinAI Research から) Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen から公開された研究論文: [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/)
+1. **[BigBird-Pegasus](https://huggingface.co/docs/transformers/model_doc/bigbird_pegasus)** (Google Research から) Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed から公開された研究論文: [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062)
+1. **[BigBird-RoBERTa](https://huggingface.co/docs/transformers/model_doc/big_bird)** (Google Research から) Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed から公開された研究論文: [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062)
+1. **[BioGpt](https://huggingface.co/docs/transformers/main/model_doc/biogpt)** (Microsoft Research AI4Science から) Renqian Luo, Liai Sun, Yingce Xia, Tao Qin, Sheng Zhang, Hoifung Poon and Tie-Yan Liu から公開された研究論文: [BioGPT: generative pre-trained transformer for biomedical text generation and mining](https://academic.oup.com/bib/advance-article/doi/10.1093/bib/bbac409/6713511?guestAccessKey=a66d9b5d-4f83-4017-bb52-405815c907b9)
+1. **[BiT](https://huggingface.co/docs/transformers/main/model_doc/bit)** (Google AI から) Alexander Kolesnikov, Lucas Beyer, Xiaohua Zhai, Joan Puigcerver, Jessica Yung, Sylvain Gelly, Neil から公開された研究論文: [Big Transfer (BiT)](https://arxiv.org/abs/1912.11370)Houlsby.
+1. **[Blenderbot](https://huggingface.co/docs/transformers/model_doc/blenderbot)** (Facebook から) Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston から公開された研究論文: [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637)
+1. **[BlenderbotSmall](https://huggingface.co/docs/transformers/model_doc/blenderbot-small)** (Facebook から) Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston から公開された研究論文: [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637)
+1. **[BLIP](https://huggingface.co/docs/transformers/main/model_doc/blip)** (Salesforce から) Junnan Li, Dongxu Li, Caiming Xiong, Steven Hoi から公開された研究論文: [BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation](https://arxiv.org/abs/2201.12086)
+1. **[BLOOM](https://huggingface.co/docs/transformers/model_doc/bloom)** (BigScience workshop から) [BigScience Workshop](https://bigscience.huggingface.co/) から公開されました.
+1. **[BORT](https://huggingface.co/docs/transformers/model_doc/bort)** (Alexa から) Adrian de Wynter and Daniel J. Perry から公開された研究論文: [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499)
+1. **[ByT5](https://huggingface.co/docs/transformers/model_doc/byt5)** (Google Research から) Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel から公開された研究論文: [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626)
+1. **[CamemBERT](https://huggingface.co/docs/transformers/model_doc/camembert)** (Inria/Facebook/Sorbonne から) Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot から公開された研究論文: [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894)
+1. **[CANINE](https://huggingface.co/docs/transformers/model_doc/canine)** (Google Research から) Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting から公開された研究論文: [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874)
+1. **[Chinese-CLIP](https://huggingface.co/docs/transformers/model_doc/chinese_clip)** (OFA-Sys から) An Yang, Junshu Pan, Junyang Lin, Rui Men, Yichang Zhang, Jingren Zhou, Chang Zhou から公開された研究論文: [Chinese CLIP: Contrastive Vision-Language Pretraining in Chinese](https://arxiv.org/abs/2211.01335)
+1. **[CLIP](https://huggingface.co/docs/transformers/model_doc/clip)** (OpenAI から) Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever から公開された研究論文: [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020)
+1. **[CLIPSeg](https://huggingface.co/docs/transformers/model_doc/clipseg)** (University of Göttingen から) Timo Lüddecke and Alexander Ecker から公開された研究論文: [Image Segmentation Using Text and Image Prompts](https://arxiv.org/abs/2112.10003)
+1. **[CodeGen](https://huggingface.co/docs/transformers/model_doc/codegen)** (Salesforce から) Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Savarese, Caiming Xiong から公開された研究論文: [A Conversational Paradigm for Program Synthesis](https://arxiv.org/abs/2203.13474)
+1. **[Conditional DETR](https://huggingface.co/docs/transformers/model_doc/conditional_detr)** (Microsoft Research Asia から) Depu Meng, Xiaokang Chen, Zejia Fan, Gang Zeng, Houqiang Li, Yuhui Yuan, Lei Sun, Jingdong Wang から公開された研究論文: [Conditional DETR for Fast Training Convergence](https://arxiv.org/abs/2108.06152)
+1. **[ConvBERT](https://huggingface.co/docs/transformers/model_doc/convbert)** (YituTech から) Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan から公開された研究論文: [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496)
+1. **[ConvNeXT](https://huggingface.co/docs/transformers/model_doc/convnext)** (Facebook AI から) Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie から公開された研究論文: [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545)
+1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CPM](https://huggingface.co/docs/transformers/model_doc/cpm)** (Tsinghua University から) Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun から公開された研究論文: [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413)
+1. **[CTRL](https://huggingface.co/docs/transformers/model_doc/ctrl)** (Salesforce から) Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher から公開された研究論文: [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858)
+1. **[CvT](https://huggingface.co/docs/transformers/model_doc/cvt)** (Microsoft から) Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang から公開された研究論文: [CvT: Introducing Convolutions to Vision Transformers](https://arxiv.org/abs/2103.15808)
+1. **[Data2Vec](https://huggingface.co/docs/transformers/model_doc/data2vec)** (Facebook から) Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli から公開された研究論文: [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555)
+1. **[DeBERTa](https://huggingface.co/docs/transformers/model_doc/deberta)** (Microsoft から) Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen から公開された研究論文: [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654)
+1. **[DeBERTa-v2](https://huggingface.co/docs/transformers/model_doc/deberta-v2)** (Microsoft から) Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen から公開された研究論文: [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654)
+1. **[Decision Transformer](https://huggingface.co/docs/transformers/model_doc/decision_transformer)** (Berkeley/Facebook/Google から) Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch から公開された研究論文: [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345)
+1. **[Deformable DETR](https://huggingface.co/docs/transformers/model_doc/deformable_detr)** (SenseTime Research から) Xizhou Zhu, Weijie Su, Lewei Lu, Bin Li, Xiaogang Wang, Jifeng Dai から公開された研究論文: [Deformable DETR: Deformable Transformers for End-to-End Object Detection](https://arxiv.org/abs/2010.04159)
+1. **[DeiT](https://huggingface.co/docs/transformers/model_doc/deit)** (Facebook から) Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou から公開された研究論文: [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877)
+1. **[DETR](https://huggingface.co/docs/transformers/model_doc/detr)** (Facebook から) Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko から公開された研究論文: [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872)
+1. **[DialoGPT](https://huggingface.co/docs/transformers/model_doc/dialogpt)** (Microsoft Research から) Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan から公開された研究論文: [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536)
+1. **[DiNAT](https://huggingface.co/docs/transformers/model_doc/dinat)** (SHI Labs から) Ali Hassani and Humphrey Shi から公開された研究論文: [Dilated Neighborhood Attention Transformer](https://arxiv.org/abs/2209.15001)
+1. **[DistilBERT](https://huggingface.co/docs/transformers/model_doc/distilbert)** (HuggingFace から), Victor Sanh, Lysandre Debut and Thomas Wolf. 同じ手法で GPT2, RoBERTa と Multilingual BERT の圧縮を行いました.圧縮されたモデルはそれぞれ [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation)、[DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation)、[DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) と名付けられました. 公開された研究論文: [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108)
+1. **[DiT](https://huggingface.co/docs/transformers/model_doc/dit)** (Microsoft Research から) Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei から公開された研究論文: [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378)
+1. **[Donut](https://huggingface.co/docs/transformers/model_doc/donut)** (NAVER から), Geewook Kim, Teakgyu Hong, Moonbin Yim, Jeongyeon Nam, Jinyoung Park, Jinyeong Yim, Wonseok Hwang, Sangdoo Yun, Dongyoon Han, Seunghyun Park から公開された研究論文: [OCR-free Document Understanding Transformer](https://arxiv.org/abs/2111.15664)
+1. **[DPR](https://huggingface.co/docs/transformers/model_doc/dpr)** (Facebook から) Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih から公開された研究論文: [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906)
+1. **[DPT](https://huggingface.co/docs/transformers/master/model_doc/dpt)** (Intel Labs から) René Ranftl, Alexey Bochkovskiy, Vladlen Koltun から公開された研究論文: [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413)
+1. **[EfficientNet](https://huggingface.co/docs/transformers/model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://arxiv.org/abs/1905.11946) by Mingxing Tan and Quoc V. Le.
+1. **[ELECTRA](https://huggingface.co/docs/transformers/model_doc/electra)** (Google Research/Stanford University から) Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning から公開された研究論文: [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555)
+1. **[EncoderDecoder](https://huggingface.co/docs/transformers/model_doc/encoder-decoder)** (Google Research から) Sascha Rothe, Shashi Narayan, Aliaksei Severyn から公開された研究論文: [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461)
+1. **[ERNIE](https://huggingface.co/docs/transformers/model_doc/ernie)** (Baidu から) Yu Sun, Shuohuan Wang, Yukun Li, Shikun Feng, Xuyi Chen, Han Zhang, Xin Tian, Danxiang Zhu, Hao Tian, Hua Wu から公開された研究論文: [ERNIE: Enhanced Representation through Knowledge Integration](https://arxiv.org/abs/1904.09223)
+1. **[ESM](https://huggingface.co/docs/transformers/model_doc/esm)** (Meta AI から) はトランスフォーマープロテイン言語モデルです. **ESM-1b** は Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott, C. Lawrence Zitnick, Jerry Ma, and Rob Fergus から公開された研究論文: [Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118). **ESM-1v** は Joshua Meier, Roshan Rao, Robert Verkuil, Jason Liu, Tom Sercu and Alexander Rives から公開された研究論文: [Language models enable zero-shot prediction of the effects of mutations on protein function](https://doi.org/10.1101/2021.07.09.450648). **ESM-2** と **ESMFold** は Zeming Lin, Halil Akin, Roshan Rao, Brian Hie, Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido, Alexander Rives から公開された研究論文: [Language models of protein sequences at the scale of evolution enable accurate structure prediction](https://doi.org/10.1101/2022.07.20.500902)
+1. **[FLAN-T5](https://huggingface.co/docs/transformers/model_doc/flan-t5)** (Google AI から) Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V から公開されたレポジトリー [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-t5-checkpoints) Le, and Jason Wei
+1. **[FlauBERT](https://huggingface.co/docs/transformers/model_doc/flaubert)** (CNRS から) Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab から公開された研究論文: [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372)
+1. **[FLAVA](https://huggingface.co/docs/transformers/model_doc/flava)** (Facebook AI から) Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela から公開された研究論文: [FLAVA: A Foundational Language And Vision Alignment Model](https://arxiv.org/abs/2112.04482)
+1. **[FNet](https://huggingface.co/docs/transformers/model_doc/fnet)** (Google Research から) James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon から公開された研究論文: [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824)
+1. **[Funnel Transformer](https://huggingface.co/docs/transformers/model_doc/funnel)** (CMU/Google Brain から) Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le から公開された研究論文: [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236)
+1. **[GIT](https://huggingface.co/docs/transformers/main/model_doc/git)** (Microsoft Research から) Jianfeng Wang, Zhengyuan Yang, Xiaowei Hu, Linjie Li, Kevin Lin, Zhe Gan, Zicheng Liu, Ce Liu, Lijuan Wang. から公開された研究論文 [GIT: A Generative Image-to-text Transformer for Vision and Language](https://arxiv.org/abs/2205.14100)
+1. **[GLPN](https://huggingface.co/docs/transformers/model_doc/glpn)** (KAIST から) Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim から公開された研究論文: [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436)
+1. **[GPT](https://huggingface.co/docs/transformers/model_doc/openai-gpt)** (OpenAI から) Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever から公開された研究論文: [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/)
+1. **[GPT Neo](https://huggingface.co/docs/transformers/model_doc/gpt_neo)** (EleutherAI から) Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy から公開されたレポジトリー : [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo)
+1. **[GPT NeoX](https://huggingface.co/docs/transformers/model_doc/gpt_neox)** (EleutherAI から) Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach から公開された研究論文: [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://arxiv.org/abs/2204.06745)
+1. **[GPT NeoX Japanese](https://huggingface.co/docs/transformers/model_doc/gpt_neox_japanese)** (ABEJA から) Shinya Otani, Takayoshi Makabe, Anuj Arora, and Kyo Hattori からリリース.
+1. **[GPT-2](https://huggingface.co/docs/transformers/model_doc/gpt2)** (OpenAI から) Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever から公開された研究論文: [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/)
+1. **[GPT-J](https://huggingface.co/docs/transformers/model_doc/gptj)** (EleutherAI から) Ben Wang and Aran Komatsuzaki から公開されたレポジトリー [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/)
+1. **[GPT-Sw3](https://huggingface.co/docs/transformers/main/model_doc/gpt-sw3)** (AI-Sweden から) Ariel Ekgren, Amaru Cuba Gyllensten, Evangelia Gogoulou, Alice Heiman, Severine Verlinden, Joey Öhman, Fredrik Carlsson, Magnus Sahlgren から公開された研究論文: [Lessons Learned from GPT-SW3: Building the First Large-Scale Generative Language Model for Swedish](http://www.lrec-conf.org/proceedings/lrec2022/pdf/2022.lrec-1.376.pdf)
+1. **[GroupViT](https://huggingface.co/docs/transformers/model_doc/groupvit)** (UCSD, NVIDIA から) Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang から公開された研究論文: [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://arxiv.org/abs/2202.11094)
+1. **[Hubert](https://huggingface.co/docs/transformers/model_doc/hubert)** (Facebook から) Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed から公開された研究論文: [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447)
+1. **[I-BERT](https://huggingface.co/docs/transformers/model_doc/ibert)** (Berkeley から) Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer から公開された研究論文: [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321)
+1. **[ImageGPT](https://huggingface.co/docs/transformers/model_doc/imagegpt)** (OpenAI から) Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever から公開された研究論文: [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/)
+1. **[Jukebox](https://huggingface.co/docs/transformers/model_doc/jukebox)** (OpenAI から) Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford, Ilya Sutskever から公開された研究論文: [Jukebox: A Generative Model for Music](https://arxiv.org/pdf/2005.00341.pdf)
+1. **[LayoutLM](https://huggingface.co/docs/transformers/model_doc/layoutlm)** (Microsoft Research Asia から) Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou から公開された研究論文: [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318)
+1. **[LayoutLMv2](https://huggingface.co/docs/transformers/model_doc/layoutlmv2)** (Microsoft Research Asia から) Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou から公開された研究論文: [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740)
+1. **[LayoutLMv3](https://huggingface.co/docs/transformers/model_doc/layoutlmv3)** (Microsoft Research Asia から) Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei から公開された研究論文: [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://arxiv.org/abs/2204.08387)
+1. **[LayoutXLM](https://huggingface.co/docs/transformers/model_doc/layoutxlm)** (Microsoft Research Asia から) Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei から公開された研究論文: [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836)
+1. **[LED](https://huggingface.co/docs/transformers/model_doc/led)** (AllenAI から) Iz Beltagy, Matthew E. Peters, Arman Cohan から公開された研究論文: [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150)
+1. **[LeViT](https://huggingface.co/docs/transformers/model_doc/levit)** (Meta AI から) Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze から公開された研究論文: [LeViT: A Vision Transformer in ConvNet's Clothing for Faster Inference](https://arxiv.org/abs/2104.01136)
+1. **[LiLT](https://huggingface.co/docs/transformers/model_doc/lilt)** (South China University of Technology から) Jiapeng Wang, Lianwen Jin, Kai Ding から公開された研究論文: [LiLT: A Simple yet Effective Language-Independent Layout Transformer for Structured Document Understanding](https://arxiv.org/abs/2202.13669)
+1. **[Longformer](https://huggingface.co/docs/transformers/model_doc/longformer)** (AllenAI から) Iz Beltagy, Matthew E. Peters, Arman Cohan から公開された研究論文: [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150)
+1. **[LongT5](https://huggingface.co/docs/transformers/model_doc/longt5)** (Google AI から) Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung, Yinfei Yang から公開された研究論文: [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://arxiv.org/abs/2112.07916)
+1. **[LUKE](https://huggingface.co/docs/transformers/model_doc/luke)** (Studio Ousia から) Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto から公開された研究論文: [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057)
+1. **[LXMERT](https://huggingface.co/docs/transformers/model_doc/lxmert)** (UNC Chapel Hill から) Hao Tan and Mohit Bansal から公開された研究論文: [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490)
+1. **[M-CTC-T](https://huggingface.co/docs/transformers/model_doc/mctct)** (Facebook から) Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert から公開された研究論文: [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://arxiv.org/abs/2111.00161)
+1. **[M2M100](https://huggingface.co/docs/transformers/model_doc/m2m_100)** (Facebook から) Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin から公開された研究論文: [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125)
+1. **[MarianMT](https://huggingface.co/docs/transformers/model_doc/marian)** Jörg Tiedemann から. [OPUS](http://opus.nlpl.eu/) を使いながら学習された "Machine translation" (マシントランスレーション) モデル. [Marian Framework](https://marian-nmt.github.io/) はMicrosoft Translator Team が現在開発中です.
+1. **[MarkupLM](https://huggingface.co/docs/transformers/model_doc/markuplm)** (Microsoft Research Asia から) Junlong Li, Yiheng Xu, Lei Cui, Furu Wei から公開された研究論文: [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document Understanding](https://arxiv.org/abs/2110.08518)
+1. **[Mask2Former](https://huggingface.co/docs/transformers/main/model_doc/mask2former)** (FAIR and UIUC から) Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar. から公開された研究論文 [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527)
+1. **[MaskFormer](https://huggingface.co/docs/transformers/model_doc/maskformer)** (Meta and UIUC から) Bowen Cheng, Alexander G. Schwing, Alexander Kirillov から公開された研究論文: [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278)
+1. **[mBART](https://huggingface.co/docs/transformers/model_doc/mbart)** (Facebook から) Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer から公開された研究論文: [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210)
+1. **[mBART-50](https://huggingface.co/docs/transformers/model_doc/mbart)** (Facebook から) Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan から公開された研究論文: [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401)
+1. **[Megatron-BERT](https://huggingface.co/docs/transformers/model_doc/megatron-bert)** (NVIDIA から) Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro から公開された研究論文: [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053)
+1. **[Megatron-GPT2](https://huggingface.co/docs/transformers/model_doc/megatron_gpt2)** (NVIDIA から) Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro から公開された研究論文: [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053)
+1. **[mLUKE](https://huggingface.co/docs/transformers/model_doc/mluke)** (Studio Ousia から) Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka から公開された研究論文: [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151)
+1. **[MobileBERT](https://huggingface.co/docs/transformers/model_doc/mobilebert)** (CMU/Google Brain から) Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny Zhou から公開された研究論文: [MobileBERT: a Compact Task-Agnostic BERT for Resource-Limited Devices](https://arxiv.org/abs/2004.02984)
+1. **[MobileNetV1](https://huggingface.co/docs/transformers/model_doc/mobilenet_v1)** (Google Inc. から) Andrew G. Howard, Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, Marco Andreetto, Hartwig Adam から公開された研究論文: [MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications](https://arxiv.org/abs/1704.04861)
+1. **[MobileNetV2](https://huggingface.co/docs/transformers/model_doc/mobilenet_v2)** (Google Inc. から) Mark Sandler, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, Liang-Chieh Chen から公開された研究論文: [MobileNetV2: Inverted Residuals and Linear Bottlenecks](https://arxiv.org/abs/1801.04381)
+1. **[MobileViT](https://huggingface.co/docs/transformers/model_doc/mobilevit)** (Apple から) Sachin Mehta and Mohammad Rastegari から公開された研究論文: [MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer](https://arxiv.org/abs/2110.02178)
+1. **[MPNet](https://huggingface.co/docs/transformers/model_doc/mpnet)** (Microsoft Research から) Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu から公開された研究論文: [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297)
+1. **[MT5](https://huggingface.co/docs/transformers/model_doc/mt5)** (Google AI から) Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel から公開された研究論文: [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934)
+1. **[MVP](https://huggingface.co/docs/transformers/model_doc/mvp)** (RUC AI Box から) Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen から公開された研究論文: [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://arxiv.org/abs/2206.12131)
+1. **[NAT](https://huggingface.co/docs/transformers/model_doc/nat)** (SHI Labs から) Ali Hassani, Steven Walton, Jiachen Li, Shen Li, and Humphrey Shi から公開された研究論文: [Neighborhood Attention Transformer](https://arxiv.org/abs/2204.07143)
+1. **[Nezha](https://huggingface.co/docs/transformers/model_doc/nezha)** (Huawei Noah’s Ark Lab から) Junqiu Wei, Xiaozhe Ren, Xiaoguang Li, Wenyong Huang, Yi Liao, Yasheng Wang, Jiashu Lin, Xin Jiang, Xiao Chen and Qun Liu から公開された研究論文: [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://arxiv.org/abs/1909.00204)
+1. **[NLLB](https://huggingface.co/docs/transformers/model_doc/nllb)** (Meta から) the NLLB team から公開された研究論文: [No Language Left Behind: Scaling Human-Centered Machine Translation](https://arxiv.org/abs/2207.04672)
+1. **[Nyströmformer](https://huggingface.co/docs/transformers/model_doc/nystromformer)** (the University of Wisconsin - Madison から) Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh から公開された研究論文: [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902)
+1. **[OneFormer](https://huggingface.co/docs/transformers/main/model_doc/oneformer)** (SHI Labs から) Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi から公開された研究論文: [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220)
+1. **[OPT](https://huggingface.co/docs/transformers/master/model_doc/opt)** (Meta AI から) Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al から公開された研究論文: [OPT: Open Pre-trained Transformer Language Models](https://arxiv.org/abs/2205.01068)
+1. **[OWL-ViT](https://huggingface.co/docs/transformers/model_doc/owlvit)** (Google AI から) Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby から公開された研究論文: [Simple Open-Vocabulary Object Detection with Vision Transformers](https://arxiv.org/abs/2205.06230)
+1. **[Pegasus](https://huggingface.co/docs/transformers/model_doc/pegasus)** (Google から) Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu から公開された研究論文: [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777)
+1. **[PEGASUS-X](https://huggingface.co/docs/transformers/model_doc/pegasus_x)** (Google から) Jason Phang, Yao Zhao, and Peter J. Liu から公開された研究論文: [Investigating Efficiently Extending Transformers for Long Input Summarization](https://arxiv.org/abs/2208.04347)
+1. **[Perceiver IO](https://huggingface.co/docs/transformers/model_doc/perceiver)** (Deepmind から) Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira から公開された研究論文: [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795)
+1. **[PhoBERT](https://huggingface.co/docs/transformers/model_doc/phobert)** (VinAI Research から) Dat Quoc Nguyen and Anh Tuan Nguyen から公開された研究論文: [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/)
+1. **[PLBart](https://huggingface.co/docs/transformers/model_doc/plbart)** (UCLA NLP から) Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang から公開された研究論文: [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333)
+1. **[PoolFormer](https://huggingface.co/docs/transformers/model_doc/poolformer)** (Sea AI Labs から) Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng から公開された研究論文: [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418)
+1. **[ProphetNet](https://huggingface.co/docs/transformers/model_doc/prophetnet)** (Microsoft Research から) Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou から公開された研究論文: [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063)
+1. **[QDQBert](https://huggingface.co/docs/transformers/model_doc/qdqbert)** (NVIDIA から) Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius から公開された研究論文: [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602)
+1. **[RAG](https://huggingface.co/docs/transformers/model_doc/rag)** (Facebook から) Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela から公開された研究論文: [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://arxiv.org/abs/2005.11401)
+1. **[REALM](https://huggingface.co/docs/transformers/model_doc/realm.html)** (Google Research から) Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang から公開された研究論文: [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909)
+1. **[Reformer](https://huggingface.co/docs/transformers/model_doc/reformer)** (Google Research から) Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya から公開された研究論文: [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451)
+1. **[RegNet](https://huggingface.co/docs/transformers/model_doc/regnet)** (META Platforms から) Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár から公開された研究論文: [Designing Network Design Space](https://arxiv.org/abs/2003.13678)
+1. **[RemBERT](https://huggingface.co/docs/transformers/model_doc/rembert)** (Google Research から) Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder から公開された研究論文: [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821)
+1. **[ResNet](https://huggingface.co/docs/transformers/model_doc/resnet)** (Microsoft Research から) Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun から公開された研究論文: [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385)
+1. **[RoBERTa](https://huggingface.co/docs/transformers/model_doc/roberta)** (Facebook から), Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov から公開された研究論文: [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692)
+1. **[RoBERTa-PreLayerNorm](https://huggingface.co/docs/transformers/main/model_doc/roberta-prelayernorm)** (Facebook から) Myle Ott, Sergey Edunov, Alexei Baevski, Angela Fan, Sam Gross, Nathan Ng, David Grangier, Michael Auli から公開された研究論文: [fairseq: A Fast, Extensible Toolkit for Sequence Modeling](https://arxiv.org/abs/1904.01038)
+1. **[RoCBert](https://huggingface.co/docs/transformers/main/model_doc/roc_bert)** (WeChatAI から) HuiSu, WeiweiShi, XiaoyuShen, XiaoZhou, TuoJi, JiaruiFang, JieZhou から公開された研究論文: [RoCBert: Robust Chinese Bert with Multimodal Contrastive Pretraining](https://aclanthology.org/2022.acl-long.65.pdf)
+1. **[RoFormer](https://huggingface.co/docs/transformers/model_doc/roformer)** (ZhuiyiTechnology から), Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu から公開された研究論文: [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864)
+1. **[SegFormer](https://huggingface.co/docs/transformers/model_doc/segformer)** (NVIDIA から) Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo から公開された研究論文: [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203)
+1. **[SEW](https://huggingface.co/docs/transformers/model_doc/sew)** (ASAPP から) Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi から公開された研究論文: [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870)
+1. **[SEW-D](https://huggingface.co/docs/transformers/model_doc/sew_d)** (ASAPP から) Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi から公開された研究論文: [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870)
+1. **[SpeechToTextTransformer](https://huggingface.co/docs/transformers/model_doc/speech_to_text)** (Facebook から), Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino から公開された研究論文: [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171)
+1. **[SpeechToTextTransformer2](https://huggingface.co/docs/transformers/model_doc/speech_to_text_2)** (Facebook から), Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau から公開された研究論文: [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678)
+1. **[Splinter](https://huggingface.co/docs/transformers/model_doc/splinter)** (Tel Aviv University から), Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy から公開された研究論文: [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438)
+1. **[SqueezeBERT](https://huggingface.co/docs/transformers/model_doc/squeezebert)** (Berkeley から) Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer から公開された研究論文: [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316)
+1. **[Swin Transformer](https://huggingface.co/docs/transformers/model_doc/swin)** (Microsoft から) Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo から公開された研究論文: [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030)
+1. **[Swin Transformer V2](https://huggingface.co/docs/transformers/model_doc/swinv2)** (Microsoft から) Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo から公開された研究論文: [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883)
+1. **[Swin2SR](https://huggingface.co/docs/transformers/main/model_doc/swin2sr)** (University of Würzburg から) Marcos V. Conde, Ui-Jin Choi, Maxime Burchi, Radu Timofte から公開された研究論文: [Swin2SR: SwinV2 Transformer for Compressed Image Super-Resolution and Restoration](https://arxiv.org/abs/2209.11345)
+1. **[SwitchTransformers](https://huggingface.co/docs/transformers/main/model_doc/switch_transformers)** (Google から) William Fedus, Barret Zoph, Noam Shazeer から公開された研究論文: [Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity](https://arxiv.org/abs/2101.03961)
+1. **[T5](https://huggingface.co/docs/transformers/model_doc/t5)** (Google AI から) Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu から公開された研究論文: [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683)
+1. **[T5v1.1](https://huggingface.co/docs/transformers/model_doc/t5v1.1)** (Google AI から) Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu から公開されたレポジトリー [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511)
+1. **[Table Transformer](https://huggingface.co/docs/transformers/model_doc/table-transformer)** (Microsoft Research から) Brandon Smock, Rohith Pesala, Robin Abraham から公開された研究論文: [PubTables-1M: Towards Comprehensive Table Extraction From Unstructured Documents](https://arxiv.org/abs/2110.00061)
+1. **[TAPAS](https://huggingface.co/docs/transformers/model_doc/tapas)** (Google AI から) Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos から公開された研究論文: [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349)
+1. **[TAPEX](https://huggingface.co/docs/transformers/model_doc/tapex)** (Microsoft Research から) Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou から公開された研究論文: [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653)
+1. **[Time Series Transformer](https://huggingface.co/docs/transformers/model_doc/time_series_transformer)** (HuggingFace から).
+1. **[TimeSformer](https://huggingface.co/docs/transformers/main/model_doc/timesformer)** (Facebook から) Gedas Bertasius, Heng Wang, Lorenzo Torresani から公開された研究論文: [Is Space-Time Attention All You Need for Video Understanding?](https://arxiv.org/abs/2102.05095)
+1. **[Trajectory Transformer](https://huggingface.co/docs/transformers/model_doc/trajectory_transformers)** (the University of California at Berkeley から) Michael Janner, Qiyang Li, Sergey Levine から公開された研究論文: [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://arxiv.org/abs/2106.02039)
+1. **[Transformer-XL](https://huggingface.co/docs/transformers/model_doc/transfo-xl)** (Google/CMU から) Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov から公開された研究論文: [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860)
+1. **[TrOCR](https://huggingface.co/docs/transformers/model_doc/trocr)** (Microsoft から), Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei から公開された研究論文: [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282)
+1. **[UL2](https://huggingface.co/docs/transformers/model_doc/ul2)** (Google Research から) Yi Tay, Mostafa Dehghani, Vinh Q から公開された研究論文: [Unifying Language Learning Paradigms](https://arxiv.org/abs/2205.05131v1) Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler
+1. **[UniSpeech](https://huggingface.co/docs/transformers/model_doc/unispeech)** (Microsoft Research から) Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang から公開された研究論文: [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597)
+1. **[UniSpeechSat](https://huggingface.co/docs/transformers/model_doc/unispeech-sat)** (Microsoft Research から) Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu から公開された研究論文: [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752)
+1. **[UPerNet](https://huggingface.co/docs/transformers/main/model_doc/upernet)** (Peking University から) Tete Xiao, Yingcheng Liu, Bolei Zhou, Yuning Jiang, Jian Sun. から公開された研究論文 [Unified Perceptual Parsing for Scene Understanding](https://arxiv.org/abs/1807.10221)
+1. **[VAN](https://huggingface.co/docs/transformers/model_doc/van)** (Tsinghua University and Nankai University から) Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu から公開された研究論文: [Visual Attention Network](https://arxiv.org/abs/2202.09741)
+1. **[VideoMAE](https://huggingface.co/docs/transformers/model_doc/videomae)** (Multimedia Computing Group, Nanjing University から) Zhan Tong, Yibing Song, Jue Wang, Limin Wang から公開された研究論文: [VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training](https://arxiv.org/abs/2203.12602)
+1. **[ViLT](https://huggingface.co/docs/transformers/model_doc/vilt)** (NAVER AI Lab/Kakao Enterprise/Kakao Brain から) Wonjae Kim, Bokyung Son, Ildoo Kim から公開された研究論文: [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334)
+1. **[Vision Transformer (ViT)](https://huggingface.co/docs/transformers/model_doc/vit)** (Google AI から) Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby から公開された研究論文: [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929)
+1. **[VisualBERT](https://huggingface.co/docs/transformers/model_doc/visual_bert)** (UCLA NLP から) Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang から公開された研究論文: [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557)
+1. **[ViT Hybrid](https://huggingface.co/docs/transformers/main/model_doc/vit_hybrid)** (Google AI から) Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby から公開された研究論文: [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929)
+1. **[ViTMAE](https://huggingface.co/docs/transformers/model_doc/vit_mae)** (Meta AI から) Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick から公開された研究論文: [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377)
+1. **[ViTMSN](https://huggingface.co/docs/transformers/model_doc/vit_msn)** (Meta AI から) Mahmoud Assran, Mathilde Caron, Ishan Misra, Piotr Bojanowski, Florian Bordes, Pascal Vincent, Armand Joulin, Michael Rabbat, Nicolas Ballas から公開された研究論文: [Masked Siamese Networks for Label-Efficient Learning](https://arxiv.org/abs/2204.07141)
+1. **[Wav2Vec2](https://huggingface.co/docs/transformers/model_doc/wav2vec2)** (Facebook AI から) Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli から公開された研究論文: [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477)
+1. **[Wav2Vec2-Conformer](https://huggingface.co/docs/transformers/model_doc/wav2vec2-conformer)** (Facebook AI から) Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Sravya Popuri, Dmytro Okhonko, Juan Pino から公開された研究論文: [FAIRSEQ S2T: Fast Speech-to-Text Modeling with FAIRSEQ](https://arxiv.org/abs/2010.05171)
+1. **[Wav2Vec2Phoneme](https://huggingface.co/docs/transformers/model_doc/wav2vec2_phoneme)** (Facebook AI から) Qiantong Xu, Alexei Baevski, Michael Auli から公開された研究論文: [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680)
+1. **[WavLM](https://huggingface.co/docs/transformers/model_doc/wavlm)** (Microsoft Research から) Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei から公開された研究論文: [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900)
+1. **[Whisper](https://huggingface.co/docs/transformers/model_doc/whisper)** (OpenAI から) Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever から公開された研究論文: [Robust Speech Recognition via Large-Scale Weak Supervision](https://cdn.openai.com/papers/whisper.pdf)
+1. **[X-CLIP](https://huggingface.co/docs/transformers/model_doc/xclip)** (Microsoft Research から) Bolin Ni, Houwen Peng, Minghao Chen, Songyang Zhang, Gaofeng Meng, Jianlong Fu, Shiming Xiang, Haibin Ling から公開された研究論文: [Expanding Language-Image Pretrained Models for General Video Recognition](https://arxiv.org/abs/2208.02816)
+1. **[XGLM](https://huggingface.co/docs/transformers/model_doc/xglm)** (From Facebook AI) Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li から公開された研究論文: [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668)
+1. **[XLM](https://huggingface.co/docs/transformers/model_doc/xlm)** (Facebook から) Guillaume Lample and Alexis Conneau から公開された研究論文: [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291)
+1. **[XLM-ProphetNet](https://huggingface.co/docs/transformers/model_doc/xlm-prophetnet)** (Microsoft Research から) Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou から公開された研究論文: [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063)
+1. **[XLM-RoBERTa](https://huggingface.co/docs/transformers/model_doc/xlm-roberta)** (Facebook AI から), Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov から公開された研究論文: [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116)
+1. **[XLM-RoBERTa-XL](https://huggingface.co/docs/transformers/model_doc/xlm-roberta-xl)** (Facebook AI から), Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau から公開された研究論文: [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572)
+1. **[XLNet](https://huggingface.co/docs/transformers/model_doc/xlnet)** (Google/CMU から) Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le から公開された研究論文: [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237)
+1. **[XLS-R](https://huggingface.co/docs/transformers/model_doc/xls_r)** (Facebook AI から) Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli から公開された研究論文: [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296)
+1. **[XLSR-Wav2Vec2](https://huggingface.co/docs/transformers/model_doc/xlsr_wav2vec2)** (Facebook AI から) Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli から公開された研究論文: [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979)
+1. **[YOLOS](https://huggingface.co/docs/transformers/model_doc/yolos)** (Huazhong University of Science & Technology から) Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu から公開された研究論文: [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://arxiv.org/abs/2106.00666)
+1. **[YOSO](https://huggingface.co/docs/transformers/model_doc/yoso)** (the University of Wisconsin - Madison から) Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh から公開された研究論文: [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714)
+
+
+### サポートされているフレームワーク
+
+以下のテーブルはそれぞれのモデルでサポートされているライブラリを示しています。"slow"と呼ばれるPythonトークナイザー、🤗 Tokenizers ライブラリによる"fast"トークナイザー、PyTorch, TensorFlow, Flaxの5つのそれぞれがサポートされているかを示しています。
+
+
+
+| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:-----------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| AltCLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Audio Spectrogram Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBird-Pegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BioGpt | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BiT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BLOOM | ❌ | ✅ | ✅ | ❌ | ❌ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| CANINE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Chinese-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CLIPSeg | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CodeGen | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Conditional DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNeXT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| CvT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Deformable DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DiNAT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DonutSwin | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ERNIE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ESM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FLAVA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GIT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
+| GPT NeoX Japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| GPT-Sw3 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| GroupViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Jukebox | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LayoutLMv3 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LeViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LiLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LongT5 | ❌ | ❌ | ✅ | ❌ | ✅ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M-CTC-T | ❌ | ❌ | ✅ | ❌ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MarkupLM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Mask2Former | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MaskFormerSwin | ❌ | ❌ | ❌ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Megatron-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MobileNetV1 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileNetV2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MVP | ✅ | ✅ | ✅ | ❌ | ❌ |
+| NAT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Nezha | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Nyströmformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| OPT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| OWL-ViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| PEGASUS-X | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| REALM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoBERTa-PreLayerNorm | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RoCBert | ✅ | ❌ | ✅ | ❌ | ❌ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| SegFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Swin Transformer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Swin Transformer V2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Swin2SR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SwitchTransformers | ❌ | ❌ | ✅ | ❌ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Table Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Time Series Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TimeSformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UPerNet | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VideoMAE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| VisualBERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViT Hybrid | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| ViTMSN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Whisper | ✅ | ❌ | ✅ | ✅ | ❌ |
+| X-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/installation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/installation.md
new file mode 100644
index 0000000000000000000000000000000000000000..cb4919caf50571b95ffd9bacd6292c0fdf5d6294
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/installation.md
@@ -0,0 +1,244 @@
+
+
+# インストール
+
+使用しているDeep Learningライブラリに対して、🤗 Transformersをインストールしてキャッシュを設定、そしてオプションでオフラインで実行できるように 🤗 Transformersを設定します。
+
+🤗 TransformersはPython 3.6+, PyTorch 1.1.0+, TensorFlow 2.0+, Flaxで動作確認しています。 使用しているDeep Learningライブラリに合わせて、以下のインストール方法に従ってください:
+
+* [PyTorch](https://pytorch.org/get-started/locally/)のインストール手順。
+* [TensorFlow 2.0](https://www.tensorflow.org/install/pip)のインストール手順。
+* [Flax](https://flax.readthedocs.io/en/latest/)のインストール手順。
+
+## pipでのインストール
+
+🤗 Transformersを[仮想環境](https://docs.python.org/3/library/venv.html)にインストールする必要があります。 もし、Pythonの仮想環境に馴染みがない場合は、この[ガイド](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/)をご覧ください。仮想環境によって異なるプロジェクトの管理がより簡単になり、依存関係間の互換性の問題を回避できます。
+
+まず、プロジェクトディレクトリに仮想環境を作成することから始めましょう:
+
+```bash
+python -m venv .env
+```
+
+仮想環境を起動しましょう。LinuxとMacOsの場合は以下のコマンドで起動します:
+
+```bash
+source .env/bin/activate
+```
+Windowsで仮想環境を起動します
+
+```bash
+.env/Scripts/activate
+```
+
+これで、次のコマンドで🤗 Transformersをインストールする準備が整いました:
+
+```bash
+pip install transformers
+```
+
+CPU対応のみ必要な場合、🤗 TransformersとDeep Learningライブラリを1行でインストールできるようになっていて便利です。例えば、🤗 TransformersとPyTorchを以下のように一緒にインストールできます:
+
+```bash
+pip install transformers[torch]
+```
+
+🤗 TransformersとTensorFlow 2.0:
+
+```bash
+pip install transformers[tf-cpu]
+```
+
+🤗 TransformersとFlax:
+
+```bash
+pip install transformers[flax]
+```
+
+最後に、以下のコマンドを実行することで🤗 Transformersが正しくインストールされているかを確認します。学習済みモデルがダウンロードされます:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('we love you'))"
+```
+
+その後、ラベルとスコアが出力されます:
+
+```bash
+[{'label': 'POSITIVE', 'score': 0.9998704791069031}]
+```
+
+## ソースからのインストール
+
+以下のコマンドでソースから🤗 Transformersをインストールします:
+
+```bash
+pip install git+https://github.com/huggingface/transformers
+```
+
+このコマンドは最新の安定版ではなく、開発における最新の`main`バージョンをインストールします。`main`バージョンは最新の開発状況に対応するのに便利です。例えば、最後の公式リリース以降にバグが修正されたが、新しいリリースがまだ展開されていない場合などです。しかし、これは`main`バージョンが常に安定しているとは限らないことを意味します。私たちは`main`バージョンの運用を維持するよう努め、ほとんどの問題は通常、数時間から1日以内に解決されます。もし問題に遭遇した場合は、より早く修正できるように[Issue](https://github.com/huggingface/transformers/issues)を作成してください!
+
+以下のコマンドを実行して、🤗 Transformersが正しくインストールされているかどうかを確認します:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('I love you'))"
+```
+
+## 編集可能なインストール
+
+必要に応じて、編集可能なインストールをします:
+
+* ソースコードの`main`バージョンを使います。
+* 🤗 Transformersにコントリビュートし、コードの変更をテストする必要があります。
+
+以下のコマンドでレポジトリをクローンして、🤗 Transformersをインストールします:
+
+```bash
+git clone https://github.com/huggingface/transformers.git
+cd transformers
+pip install -e .
+```
+
+上記のコマンドは、レポジトリをクローンしたフォルダとPythonのライブラリをパスをリンクします。Pythonは通常のライブラリパスに加えて、あなたがクローンしたフォルダの中も見るようになります。例えば、Pythonパッケージが通常、`~/anaconda3/envs/main/lib/python3.7/site-packages/`にインストールされている場合、Pythonはクローンしたフォルダも検索するようになります: `~/transformers/`.
+
+
+
+ライブラリーを使い続けたい場合は、transformersフォルダーを保持しつづける必要があります。
+
+
+
+これで、次のコマンドで簡単にクローンを🤗 Transformersの最新版に更新できます:
+
+```bash
+cd ~/transformers/
+git pull
+```
+
+Python環境は次回の実行時に🤗 Transformersの`main`バージョンを見つけるようになります。
+
+## condaでのインストール
+
+`conda-forge`のcondaチャンネルからインストールします:
+
+```bash
+conda install conda-forge::transformers
+```
+
+## キャッシュの設定
+
+学習済みモデルはダウンロードされ、ローカルにキャッシュされます: `~/.cache/huggingface/hub`. これはシェル環境変数`TRANSFORMERS_CACHE`で指定されるデフォルトのディレクトリです。Windowsでは、デフォルトのディレクトリは`C:\Users\username\.cache\huggingface\hub`になっています。異なるキャッシュディレクトリを指定するために、以下のシェル環境変数を変更することが可能です。優先度は以下の順番に対応します:
+
+1. シェル環境変数 (デフォルト): `HF_HUB_CACHE` または `TRANSFORMERS_CACHE`.
+2. シェル環境変数: `HF_HOME`.
+3. シェル環境変数: `XDG_CACHE_HOME` + `/huggingface`.
+
+
+
+もし、以前のバージョンのライブラリを使用していた人で、`PYTORCH_TRANSFORMERS_CACHE`または`PYTORCH_PRETRAINED_BERT_CACHE`を設定していた場合、シェル環境変数`TRANSFORMERS_CACHE`を指定しない限り🤗 Transformersはこれらのシェル環境変数を使用します。
+
+
+
+## オフラインモード
+
+🤗 Transformersはローカルファイルのみを使用することでファイアウォールやオフラインの環境でも動作させることができます。この動作を有効にするためには、環境変数`HF_HUB_OFFLINE=1`を設定します。
+
+
+
+環境変数`HF_DATASETS_OFFLINE=1`を設定し、オフライントレーニングワークフローに[🤗 Datasets](https://huggingface.co/docs/datasets/)を追加します。
+
+
+
+例えば、外部インスタンスに対してファイアウォールで保護された通常のネットワーク上でプログラムを実行する場合、通常以下のようなコマンドで実行することになります:
+
+```bash
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+オフラインインスタンスでこの同じプログラムを実行します:
+
+```bash
+HF_DATASETS_OFFLINE=1 HF_HUB_OFFLINE=1 \
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+このスクリプトは、ローカルファイルのみを検索することが分かっているので、ハングアップしたりタイムアウトを待ったりすることなく実行されるはずです。
+
+### オフラインで使用するためにモデルやトークナイザーを取得する
+
+オフラインで🤗 Transformersを使用するもう1つの方法は、前もってファイルをダウンロードしておき、オフラインで使用する必要があるときにそのローカルパスを指定することです。これには3つの方法があります:
+
+* [Model Hub](https://huggingface.co/models)のユーザーインターフェース上から↓アイコンをクリックしてファイルをダウンロードする方法。
+
+ 
+
+* [`PreTrainedModel.from_pretrained`]および[`PreTrainedModel.save_pretrained`]のワークフローを使用する方法:
+
+ 1. [`PreTrainedModel.from_pretrained`]で前もってファイルをダウンロードします:
+
+ ```py
+ >>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("bigscience/T0_3B")
+ >>> model = AutoModelForSeq2SeqLM.from_pretrained("bigscience/T0_3B")
+ ```
+
+ 2. [`PreTrainedModel.save_pretrained`]で指定されたディレクトリにファイルを保存しておきます:
+
+ ```py
+ >>> tokenizer.save_pretrained("./your/path/bigscience_t0")
+ >>> model.save_pretrained("./your/path/bigscience_t0")
+ ```
+
+ 3. オフラインにある時、[`PreTrainedModel.from_pretrained`]に指定したディレクトリからファイルをリロードします:
+
+ ```py
+ >>> tokenizer = AutoTokenizer.from_pretrained("./your/path/bigscience_t0")
+ >>> model = AutoModel.from_pretrained("./your/path/bigscience_t0")
+ ```
+
+* プログラム的に[huggingface_hub](https://github.com/huggingface/huggingface_hub/tree/main/src/huggingface_hub)ライブラリを用いて、ファイルをダウンロードする方法:
+
+ 1. 仮想環境に`huggingface_hub`ライブラリをインストールします:
+
+ ```bash
+ python -m pip install huggingface_hub
+ ```
+
+ 2. 指定のパスにファイルをダウンロードするために、[`hf_hub_download`](https://huggingface.co/docs/hub/adding-a-library#download-files-from-the-hub)関数を使用します。例えば、以下のコマンドで、[T0](https://huggingface.co/bigscience/T0_3B)モデルの`config.json`ファイルを指定のパスにダウンロードできます:
+
+ ```py
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> hf_hub_download(repo_id="bigscience/T0_3B", filename="config.json", cache_dir="./your/path/bigscience_t0")
+ ```
+
+ファイルがダウンロードされ、ローカルにキャッシュされたら、そのローカルパスを指定してファイルをロードして使用します:
+
+```py
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("./your/path/bigscience_t0/config.json")
+```
+
+
+
+Hubに保存されているファイルをダウンロードする方法の詳細については、[How to download files from the Hub](https://huggingface.co/docs/hub/how-to-downstream)セクションを参照してください。
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/audio_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/audio_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..967c716cd2f93ce104c4f6ebcedc97a9bee79963
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/audio_utils.md
@@ -0,0 +1,39 @@
+
+
+# `FeatureExtractor` 用のユーティリティ
+
+このページには、*短時間フーリエ変換* や *ログ メル スペクトログラム* などの一般的なアルゴリズムを使用して生のオーディオから特別な特徴を計算するために、オーディオ [`FeatureExtractor`] で使用できるすべてのユーティリティ関数がリストされています。
+
+これらのほとんどは、ライブラリ内のオーディオ プロセッサのコードを学習する場合にのみ役に立ちます。
+
+## オーディオ変換
+
+[[autodoc]] audio_utils.hertz_to_mel
+
+[[autodoc]] audio_utils.mel_to_hertz
+
+[[autodoc]] audio_utils.mel_filter_bank
+
+[[autodoc]] audio_utils.optimal_fft_length
+
+[[autodoc]] audio_utils.window_function
+
+[[autodoc]] audio_utils.spectrogram
+
+[[autodoc]] audio_utils.power_to_db
+
+[[autodoc]] audio_utils.amplitude_to_db
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/file_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/file_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..51a025bfc67f17f6b463294a04ba7f6111d9e77e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/file_utils.md
@@ -0,0 +1,49 @@
+
+
+# 一般的なユーティリティ
+
+このページには、ファイル `utils.py` にある Transformers の一般的なユーティリティ関数がすべてリストされています。
+
+これらのほとんどは、ライブラリで一般的なコードを学習する場合にのみ役に立ちます。
+
+## 列挙型と名前付きタプル
+
+[[autodoc]] utils.ExplicitEnum
+
+[[autodoc]] utils.PaddingStrategy
+
+[[autodoc]] utils.TensorType
+
+## 特別なデコレーター
+
+[[autodoc]] utils.add_start_docstrings
+
+[[autodoc]] utils.add_start_docstrings_to_model_forward
+
+[[autodoc]] utils.add_end_docstrings
+
+[[autodoc]] utils.add_code_sample_docstrings
+
+[[autodoc]] utils.replace_return_docstrings
+
+## 特殊なプロパティ
+
+[[autodoc]] utils.cached_property
+
+## その他のユーティリティ
+
+[[autodoc]] utils._LazyModule
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/generation_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/generation_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..1a5cc1dec079584f471ff3179c868971957ac855
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/generation_utils.md
@@ -0,0 +1,336 @@
+
+
+# 発電用ユーティリティ
+
+このページには、[`~generation.GenerationMixin.generate`] で使用されるすべてのユーティリティ関数がリストされています。
+
+## 出力を生成する
+
+[`~generation.GenerationMixin.generate`] の出力は、次のサブクラスのインスタンスです。
+[`~utils.ModelOutput`]。この出力は、返されたすべての情報を含むデータ構造です。
+[`~generation.GenerationMixin.generate`] によって作成されますが、タプルまたは辞書としても使用できます。
+
+以下に例を示します。
+
+```python
+from transformers import GPT2Tokenizer, GPT2LMHeadModel
+
+tokenizer = GPT2Tokenizer.from_pretrained("openai-community/gpt2")
+model = GPT2LMHeadModel.from_pretrained("openai-community/gpt2")
+
+inputs = tokenizer("Hello, my dog is cute and ", return_tensors="pt")
+generation_output = model.generate(**inputs, return_dict_in_generate=True, output_scores=True)
+```
+
+`generation_output` オブジェクトは、できる限り [`~generation.GenerateDecoderOnlyOutput`] です。
+以下のそのクラスのドキュメントを参照してください。これは、次の属性があることを意味します。
+
+- `sequences`: 生成されたトークンのシーケンス
+- `scores` (オプション): 各生成ステップの言語モデリング ヘッドの予測スコア
+- `hidden_states` (オプション): 生成ステップごとのモデルの隠れた状態
+- `attentions` (オプション): 生成ステップごとのモデルのアテンションの重み
+
+ここでは、`output_scores=True`を渡したので `scores` がありますが、`hidden_states` はありません。
+`attentions` は、`output_hidden_states=True`または`output_attentions=True`を渡さなかったためです。
+
+通常と同じように各属性にアクセスできます。その属性がモデルから返されなかった場合は、
+は「なし」を取得します。ここで、たとえば`generation_output.scores`は、生成されたすべての予測スコアです。
+言語モデリングのヘッドであり、`generation_output.attentions`は`None`です。
+
+`generation_output` オブジェクトをタプルとして使用する場合、`None` 値を持たない属性のみが保持されます。
+たとえば、ここには 2 つの要素、`loss`、次に`logits`があります。
+
+```python
+generation_output[:2]
+```
+
+たとえば、タプル `(generation_output.sequences,generation_output.scores)` を返します。
+
+`generation_output` オブジェクトを辞書として使用する場合、`None` を持たない属性のみが保持されます。
+ここでは、たとえば、`sequences`と`scores`という 2 つのキーがあります。
+
+ここではすべての出力タイプを文書化します。
+
+### PyTorch
+
+[[autodoc]] generation.GenerateDecoderOnlyOutput
+
+[[autodoc]] generation.GenerateEncoderDecoderOutput
+
+[[autodoc]] generation.GenerateBeamDecoderOnlyOutput
+
+[[autodoc]] generation.GenerateBeamEncoderDecoderOutput
+
+### TensorFlow
+
+[[autodoc]] generation.TFGreedySearchEncoderDecoderOutput
+
+[[autodoc]] generation.TFGreedySearchDecoderOnlyOutput
+
+[[autodoc]] generation.TFSampleEncoderDecoderOutput
+
+[[autodoc]] generation.TFSampleDecoderOnlyOutput
+
+[[autodoc]] generation.TFBeamSearchEncoderDecoderOutput
+
+[[autodoc]] generation.TFBeamSearchDecoderOnlyOutput
+
+[[autodoc]] generation.TFBeamSampleEncoderDecoderOutput
+
+[[autodoc]] generation.TFBeamSampleDecoderOnlyOutput
+
+[[autodoc]] generation.TFContrastiveSearchEncoderDecoderOutput
+
+[[autodoc]] generation.TFContrastiveSearchDecoderOnlyOutput
+
+### FLAX
+
+[[autodoc]] generation.FlaxSampleOutput
+
+[[autodoc]] generation.FlaxGreedySearchOutput
+
+[[autodoc]] generation.FlaxBeamSearchOutput
+
+## LogitsProcessor
+
+[`LogitsProcessor`] を使用して、言語モデルのヘッドの予測スコアを変更できます。
+世代。
+
+### PyTorch
+
+[[autodoc]] AlternatingCodebooksLogitsProcessor
+ - __call__
+
+[[autodoc]] ClassifierFreeGuidanceLogitsProcessor
+ - __call__
+
+[[autodoc]] EncoderNoRepeatNGramLogitsProcessor
+ - __call__
+
+[[autodoc]] EncoderRepetitionPenaltyLogitsProcessor
+ - __call__
+
+[[autodoc]] EpsilonLogitsWarper
+ - __call__
+
+[[autodoc]] EtaLogitsWarper
+ - __call__
+
+[[autodoc]] ExponentialDecayLengthPenalty
+ - __call__
+
+[[autodoc]] ForcedBOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] ForcedEOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] HammingDiversityLogitsProcessor
+ - __call__
+
+[[autodoc]] InfNanRemoveLogitsProcessor
+ - __call__
+
+[[autodoc]] LogitNormalization
+ - __call__
+
+[[autodoc]] LogitsProcessor
+ - __call__
+
+[[autodoc]] LogitsProcessorList
+ - __call__
+
+[[autodoc]] MinLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] MinNewTokensLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] NoBadWordsLogitsProcessor
+ - __call__
+
+[[autodoc]] NoRepeatNGramLogitsProcessor
+ - __call__
+
+[[autodoc]] PrefixConstrainedLogitsProcessor
+ - __call__
+
+[[autodoc]] RepetitionPenaltyLogitsProcessor
+ - __call__
+
+[[autodoc]] SequenceBiasLogitsProcessor
+ - __call__
+
+[[autodoc]] SuppressTokensAtBeginLogitsProcessor
+ - __call__
+
+[[autodoc]] SuppressTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] TemperatureLogitsWarper
+ - __call__
+
+[[autodoc]] TopKLogitsWarper
+ - __call__
+
+[[autodoc]] TopPLogitsWarper
+ - __call__
+
+[[autodoc]] TypicalLogitsWarper
+ - __call__
+
+[[autodoc]] UnbatchedClassifierFreeGuidanceLogitsProcessor
+ - __call__
+
+[[autodoc]] WhisperTimeStampLogitsProcessor
+ - __call__
+
+### TensorFlow
+
+[[autodoc]] TFForcedBOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] TFForcedEOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] TFForceTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] TFLogitsProcessor
+ - __call__
+
+[[autodoc]] TFLogitsProcessorList
+ - __call__
+
+[[autodoc]] TFLogitsWarper
+ - __call__
+
+[[autodoc]] TFMinLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] TFNoBadWordsLogitsProcessor
+ - __call__
+
+[[autodoc]] TFNoRepeatNGramLogitsProcessor
+ - __call__
+
+[[autodoc]] TFRepetitionPenaltyLogitsProcessor
+ - __call__
+
+[[autodoc]] TFSuppressTokensAtBeginLogitsProcessor
+ - __call__
+
+[[autodoc]] TFSuppressTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] TFTemperatureLogitsWarper
+ - __call__
+
+[[autodoc]] TFTopKLogitsWarper
+ - __call__
+
+[[autodoc]] TFTopPLogitsWarper
+ - __call__
+
+### FLAX
+
+[[autodoc]] FlaxForcedBOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxForcedEOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxForceTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxLogitsProcessorList
+ - __call__
+
+[[autodoc]] FlaxLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxMinLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxSuppressTokensAtBeginLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxSuppressTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxTemperatureLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxTopKLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxTopPLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxWhisperTimeStampLogitsProcessor
+ - __call__
+
+## StoppingCriteria
+
+[`StoppingCriteria`] を使用して、(EOS トークン以外の) 生成を停止するタイミングを変更できます。これは PyTorch 実装でのみ利用可能であることに注意してください。
+
+[[autodoc]] StoppingCriteria
+ - __call__
+
+[[autodoc]] StoppingCriteriaList
+ - __call__
+
+[[autodoc]] MaxLengthCriteria
+ - __call__
+
+[[autodoc]] MaxTimeCriteria
+ - __call__
+
+## Constraints
+
+[`Constraint`] を使用すると、生成時に出力に特定のトークンまたはシーケンスが含まれるように強制できます。これは PyTorch 実装でのみ利用可能であることに注意してください。
+
+[[autodoc]] Constraint
+
+[[autodoc]] PhrasalConstraint
+
+[[autodoc]] DisjunctiveConstraint
+
+[[autodoc]] ConstraintListState
+
+## BeamSearch
+
+[[autodoc]] BeamScorer
+ - process
+ - finalize
+
+[[autodoc]] BeamSearchScorer
+ - process
+ - finalize
+
+[[autodoc]] ConstrainedBeamSearchScorer
+ - process
+ - finalize
+
+## Streamers
+
+[[autodoc]] TextStreamer
+
+[[autodoc]] TextIteratorStreamer
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/image_processing_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/image_processing_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..917f86875f481260c0d86c32f8ef25bc6b129d2a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/image_processing_utils.md
@@ -0,0 +1,48 @@
+
+
+# 画像プロセッサ用ユーティリティ
+
+このページには、画像プロセッサーで使用されるすべてのユーティリティー関数がリストされています。主に機能的なものです。
+画像を処理するために使用される変換。
+
+これらのほとんどは、ライブラリ内の画像プロセッサのコードを学習する場合にのみ役に立ちます。
+
+## Image Transformations
+
+[[autodoc]] image_transforms.center_crop
+
+[[autodoc]] image_transforms.center_to_corners_format
+
+[[autodoc]] image_transforms.corners_to_center_format
+
+[[autodoc]] image_transforms.id_to_rgb
+
+[[autodoc]] image_transforms.normalize
+
+[[autodoc]] image_transforms.pad
+
+[[autodoc]] image_transforms.rgb_to_id
+
+[[autodoc]] image_transforms.rescale
+
+[[autodoc]] image_transforms.resize
+
+[[autodoc]] image_transforms.to_pil_image
+
+## ImageProcessingMixin
+
+[[autodoc]] image_processing_utils.ImageProcessingMixin
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/modeling_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/modeling_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..62aa2040c8a258cf889a5fbb2f332be2fdaf4bdb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/modeling_utils.md
@@ -0,0 +1,83 @@
+
+
+# カスタムレイヤーとユーティリティ
+
+このページには、ライブラリで使用されるすべてのカスタム レイヤーと、モデリングに提供されるユーティリティ関数がリストされます。
+
+これらのほとんどは、ライブラリ内のモデルのコードを研究する場合にのみ役に立ちます。
+
+
+## Pytorch custom modules
+
+[[autodoc]] pytorch_utils.Conv1D
+
+[[autodoc]] modeling_utils.PoolerStartLogits
+ - forward
+
+[[autodoc]] modeling_utils.PoolerEndLogits
+ - forward
+
+[[autodoc]] modeling_utils.PoolerAnswerClass
+ - forward
+
+[[autodoc]] modeling_utils.SquadHeadOutput
+
+[[autodoc]] modeling_utils.SQuADHead
+ - forward
+
+[[autodoc]] modeling_utils.SequenceSummary
+ - forward
+
+## PyTorch Helper Functions
+
+[[autodoc]] pytorch_utils.apply_chunking_to_forward
+
+[[autodoc]] pytorch_utils.find_pruneable_heads_and_indices
+
+[[autodoc]] pytorch_utils.prune_layer
+
+[[autodoc]] pytorch_utils.prune_conv1d_layer
+
+[[autodoc]] pytorch_utils.prune_linear_layer
+
+## TensorFlow custom layers
+
+[[autodoc]] modeling_tf_utils.TFConv1D
+
+[[autodoc]] modeling_tf_utils.TFSequenceSummary
+
+## TensorFlow loss functions
+
+[[autodoc]] modeling_tf_utils.TFCausalLanguageModelingLoss
+
+[[autodoc]] modeling_tf_utils.TFMaskedLanguageModelingLoss
+
+[[autodoc]] modeling_tf_utils.TFMultipleChoiceLoss
+
+[[autodoc]] modeling_tf_utils.TFQuestionAnsweringLoss
+
+[[autodoc]] modeling_tf_utils.TFSequenceClassificationLoss
+
+[[autodoc]] modeling_tf_utils.TFTokenClassificationLoss
+
+## TensorFlow Helper Functions
+
+[[autodoc]] modeling_tf_utils.get_initializer
+
+[[autodoc]] modeling_tf_utils.keras_serializable
+
+[[autodoc]] modeling_tf_utils.shape_list
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/pipelines_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/pipelines_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..833c98c4d0dc18cab391e620cea02a4d5a041a9b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/pipelines_utils.md
@@ -0,0 +1,44 @@
+
+
+# パイプライン用のユーティリティ
+
+このページには、ライブラリがパイプラインに提供するすべてのユーティリティ関数がリストされます。
+
+これらのほとんどは、ライブラリ内のモデルのコードを研究する場合にのみ役に立ちます。
+
+
+## Argument handling
+
+[[autodoc]] pipelines.ArgumentHandler
+
+[[autodoc]] pipelines.ZeroShotClassificationArgumentHandler
+
+[[autodoc]] pipelines.QuestionAnsweringArgumentHandler
+
+## Data format
+
+[[autodoc]] pipelines.PipelineDataFormat
+
+[[autodoc]] pipelines.CsvPipelineDataFormat
+
+[[autodoc]] pipelines.JsonPipelineDataFormat
+
+[[autodoc]] pipelines.PipedPipelineDataFormat
+
+## Utilities
+
+[[autodoc]] pipelines.PipelineException
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/time_series_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/time_series_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..9355ea090e14584b32f67e61a84f185cc1bc5821
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/time_series_utils.md
@@ -0,0 +1,29 @@
+
+
+# 時系列ユーティリティ
+
+このページには、時系列ベースのモデルに使用できるすべてのユーティリティ関数とクラスがリストされます。
+
+これらのほとんどは、時系列モデルのコードを研究している場合、または分散出力クラスのコレクションに追加したい場合にのみ役立ちます。
+
+## Distributional Output
+
+[[autodoc]] time_series_utils.NormalOutput
+
+[[autodoc]] time_series_utils.StudentTOutput
+
+[[autodoc]] time_series_utils.NegativeBinomialOutput
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/tokenization_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/tokenization_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..8e36e4149e278415d7a11e7195234ea2e2bfaa04
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/tokenization_utils.md
@@ -0,0 +1,42 @@
+
+
+# Utilities for Tokenizers
+
+このページには、トークナイザーによって使用されるすべてのユーティリティ関数 (主にクラス) がリストされます。
+[`~tokenization_utils_base.PreTrainedTokenizerBase`] 間の共通メソッドを実装します。
+[`PreTrainedTokenizer`] と [`PreTrainedTokenizerFast`] およびミックスイン
+[`~tokenization_utils_base.SpecialTokensMixin`]。
+
+これらのほとんどは、ライブラリ内のトークナイザーのコードを学習する場合にのみ役に立ちます。
+
+## PreTrainedTokenizerBase
+
+[[autodoc]] tokenization_utils_base.PreTrainedTokenizerBase
+ - __call__
+ - all
+
+## SpecialTokensMixin
+
+[[autodoc]] tokenization_utils_base.SpecialTokensMixin
+
+## Enums and namedtuples
+
+[[autodoc]] tokenization_utils_base.TruncationStrategy
+
+[[autodoc]] tokenization_utils_base.CharSpan
+
+[[autodoc]] tokenization_utils_base.TokenSpan
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/trainer_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/trainer_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..dddfc7dc55ee12827447217f0e65e53dac0652e7
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/internal/trainer_utils.md
@@ -0,0 +1,49 @@
+
+
+# トレーナー用ユーティリティ
+
+このページには、[`Trainer`] で使用されるすべてのユーティリティ関数がリストされています。
+
+これらのほとんどは、ライブラリ内のトレーナーのコードを学習する場合にのみ役に立ちます。
+
+## Utilities
+
+[[autodoc]] EvalPrediction
+
+[[autodoc]] IntervalStrategy
+
+[[autodoc]] enable_full_determinism
+
+[[autodoc]] set_seed
+
+[[autodoc]] torch_distributed_zero_first
+
+## Callbacks internals
+
+[[autodoc]] trainer_callback.CallbackHandler
+
+## Distributed Evaluation
+
+[[autodoc]] trainer_pt_utils.DistributedTensorGatherer
+
+## Trainer Argument Parser
+
+[[autodoc]] HfArgumentParser
+
+## Debug Utilities
+
+[[autodoc]] debug_utils.DebugUnderflowOverflow
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/llm_tutorial.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/llm_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..156a2423eedc79cc7dc88dea1b42f1204e335329
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/llm_tutorial.md
@@ -0,0 +1,223 @@
+
+
+# Generation with LLMs
+
+[[open-in-colab]]
+
+LLM、またはLarge Language Models(大規模言語モデル)は、テキスト生成の鍵となる要素です。要するに、これらは大規模な事前訓練済みトランスフォーマーモデルで、与えられた入力テキストに基づいて次の単語(または、より正確にはトークン)を予測するように訓練されています。トークンを1つずつ予測するため、モデルを呼び出すだけでは新しい文を生成するために何かより精巧なことをする必要があります。自己回帰生成を行う必要があります。
+
+自己回帰生成は、推論時の手続きで、いくつかの初期入力を与えた状態で、モデルを反復的に呼び出す手法です。🤗 Transformersでは、これは[`~generation.GenerationMixin.generate`]メソッドによって処理され、これは生成能力を持つすべてのモデルで利用可能です。
+
+このチュートリアルでは、以下のことを示します:
+
+* LLMを使用してテキストを生成する方法
+* 一般的な落とし穴を回避する方法
+* LLMを最大限に活用するための次のステップ
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください:
+
+
+```bash
+pip install transformers bitsandbytes>=0.39.0 -q
+```
+
+## Generate text
+
+[因果言語モデリング](tasks/language_modeling)のためにトレーニングされた言語モデルは、テキストトークンのシーケンスを入力として受け取り、次のトークンの確率分布を返します。
+
+
+
+ "Forward pass of an LLM"
+
+
+
+LLM(Language Model)による自己回帰生成の重要な側面の1つは、この確率分布から次のトークンを選択する方法です。このステップでは、次のイテレーションのためのトークンが得られる限り、何でも可能です。これは、確率分布から最も可能性の高いトークンを選択するだけのシンプルな方法から、結果の分布からサンプリングする前に数々の変換を適用するほど複雑な方法まで、あらゆる方法が考えられます。
+
+
+
+
+ "Autoregressive generation iteratively selects the next token from a probability distribution to generate text"
+
+
+上記のプロセスは、ある停止条件が満たされるまで反復的に繰り返されます。理想的には、停止条件はモデルによって指示され、モデルは終了シーケンス(`EOS`)トークンを出力するタイミングを学習すべきです。これがそうでない場合、生成はあらかじめ定義された最大長に達したときに停止します。
+
+トークン選択ステップと停止条件を適切に設定することは、モデルがタスクで期待どおりに振る舞うために重要です。それが、各モデルに関連付けられた [`~generation.GenerationConfig`] ファイルがある理由であり、これには優れたデフォルトの生成パラメータ化が含まれ、モデルと一緒に読み込まれます。
+
+コードについて話しましょう!
+
+
+
+基本的なLLMの使用に興味がある場合、高レベルの [`Pipeline`](pipeline_tutorial) インターフェースが良い出発点です。ただし、LLMはしばしば量子化やトークン選択ステップの細かい制御などの高度な機能が必要であり、これは [`~generation.GenerationMixin.generate`] を介して最良に行われます。LLMとの自己回帰生成はリソースが多く必要であり、適切なスループットのためにGPUで実行する必要があります。
+
+
+
+
+まず、モデルを読み込む必要があります。
+
+
+```py
+>>> from transformers import AutoModelForCausalLM
+
+>>> model = AutoModelForCausalLM.from_pretrained(
+... "openlm-research/open_llama_7b", device_map="auto", load_in_4bit=True
+... )
+```
+
+`from_pretrained` 呼び出しで2つのフラグがあることに注意してください:
+
+- `device_map` はモデルをあなたのGPUに移動させます
+- `load_in_4bit` は[4ビットの動的量子化](main_classes/quantization)を適用してリソース要件を大幅に削減します
+
+モデルを初期化する他の方法もありますが、これはLLMを始めるための良い基準です。
+
+次に、[トークナイザ](tokenizer_summary)を使用してテキスト入力を前処理する必要があります。
+
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("openlm-research/open_llama_7b")
+>>> model_inputs = tokenizer(["A list of colors: red, blue"], return_tensors="pt").to("cuda")
+```
+
+
+`model_inputs` 変数は、トークン化されたテキスト入力とアテンションマスクを保持しています。 [`~generation.GenerationMixin.generate`] は、アテンションマスクが渡されていない場合でも、最善の努力をしてそれを推測しようとしますが、できる限り渡すことをお勧めします。最適な結果を得るためです。
+
+最後に、[`~generation.GenerationMixin.generate`] メソッドを呼び出して生成されたトークンを取得し、それを表示する前にテキストに変換する必要があります。
+
+
+```py
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'A list of colors: red, blue, green, yellow, black, white, and brown'
+```
+
+これで完了です!わずかなコード行数で、LLM(Large Language Model)のパワーを活用できます。
+
+## Common pitfalls
+
+[生成戦略](generation_strategies)はたくさんあり、デフォルトの値があなたのユースケースに適していないことがあります。出力が期待通りでない場合、最も一般的な落とし穴とその回避方法のリストを作成しました。
+
+```py
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("openlm-research/open_llama_7b")
+>>> tokenizer.pad_token = tokenizer.eos_token # Llama has no pad token by default
+>>> model = AutoModelForCausalLM.from_pretrained(
+... "openlm-research/open_llama_7b", device_map="auto", load_in_4bit=True
+... )
+```
+
+### Generated output is too short/long
+
+[`~generation.GenerationConfig`] ファイルで指定されていない場合、`generate` はデフォルトで最大で 20 トークンまで返します。我々は `generate` コールで `max_new_tokens` を手動で設定することを強くお勧めします。これにより、返される新しいトークンの最大数を制御できます。LLM(正確には、[デコーダー専用モデル](https://huggingface.co/learn/nlp-course/chapter1/6?fw=pt))も出力の一部として入力プロンプトを返すことに注意してください。
+
+```py
+>>> model_inputs = tokenizer(["A sequence of numbers: 1, 2"], return_tensors="pt").to("cuda")
+
+>>> # By default, the output will contain up to 20 tokens
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'A sequence of numbers: 1, 2, 3, 4, 5'
+
+>>> # Setting `max_new_tokens` allows you to control the maximum length
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=50)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'A sequence of numbers: 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16,'
+```
+
+### Incorrect generation mode
+
+デフォルトでは、 [`~generation.GenerationConfig`] ファイルで指定されていない限り、`generate` は各イテレーションで最も可能性の高いトークンを選択します(貪欲デコーディング)。タスクに応じて、これは望ましくないことがあります。チャットボットやエッセイのような創造的なタスクでは、サンプリングが有益です。一方、音声の転写や翻訳のような入力に基づくタスクでは、貪欲デコーディングが有益です。`do_sample=True` でサンプリングを有効にできます。このトピックについての詳細は、この[ブログポスト](https://huggingface.co/blog/how-to-generate)で学ぶことができます。
+
+```py
+>>> # Set seed or reproducibility -- you don't need this unless you want full reproducibility
+>>> from transformers import set_seed
+>>> set_seed(0)
+
+>>> model_inputs = tokenizer(["I am a cat."], return_tensors="pt").to("cuda")
+
+>>> # LLM + greedy decoding = repetitive, boring output
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'I am a cat. I am a cat. I am a cat. I am a cat'
+
+>>> # With sampling, the output becomes more creative!
+>>> generated_ids = model.generate(**model_inputs, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'I am a cat.\nI just need to be. I am always.\nEvery time'
+```
+
+### Wrong padding side
+
+LLM(Large Language Models)は[デコーダー専用](https://huggingface.co/learn/nlp-course/chapter1/6?fw=pt)のアーキテクチャであり、入力プロンプトを繰り返し処理することを意味します。入力が同じ長さでない場合、それらをパディングする必要があります。LLMはパッドトークンからの続きを学習していないため、入力は左パディングする必要があります。また、生成に対して注目マスクを渡し忘れないようにしてください!
+
+
+```py
+>>> # The tokenizer initialized above has right-padding active by default: the 1st sequence,
+>>> # which is shorter, has padding on the right side. Generation fails.
+>>> model_inputs = tokenizer(
+... ["1, 2, 3", "A, B, C, D, E"], padding=True, return_tensors="pt"
+... ).to("cuda")
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids[0], skip_special_tokens=True)[0]
+''
+
+>>> # With left-padding, it works as expected!
+>>> tokenizer = AutoTokenizer.from_pretrained("openlm-research/open_llama_7b", padding_side="left")
+>>> tokenizer.pad_token = tokenizer.eos_token # Llama has no pad token by default
+>>> model_inputs = tokenizer(
+... ["1, 2, 3", "A, B, C, D, E"], padding=True, return_tensors="pt"
+... ).to("cuda")
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'1, 2, 3, 4, 5, 6,'
+```
+
+## Further resources
+
+オートリグレッシブ生成プロセスは比較的簡単ですが、LLMを最大限に活用することは多くの要素が絡むため、挑戦的な試みとなります。LLMの使用と理解をさらに深めるための次のステップについては以下のリソースをご覧ください。
+
+
+### Advanced generate usage
+
+1. [ガイド](generation_strategies):異なる生成方法を制御する方法、生成構成ファイルの設定方法、出力のストリーミング方法についてのガイド;
+2. [`~generation.GenerationConfig`]、[`~generation.GenerationMixin.generate`]、および[生成関連クラス](internal/generation_utils)に関するAPIリファレンス。
+
+### LLM leaderboards
+
+1. [Open LLM リーダーボード](https://huggingface.co/spaces/HuggingFaceH4/open_llm_leaderboard):オープンソースモデルの品質に焦点を当てたリーダーボード;
+2. [Open LLM-Perf リーダーボード](https://huggingface.co/spaces/optimum/llm-perf-leaderboard):LLMのスループットに焦点を当てたリーダーボード。
+
+### Latency and throughput
+
+1. [ガイド](main_classes/quantization):ダイナミッククオンタイズに関するガイド。これによりメモリ要件を劇的に削減する方法が示されています。
+
+### Related libraries
+
+1. [`text-generation-inference`](https://github.com/huggingface/text-generation-inference):LLM用の本番向けサーバー;
+2. [`optimum`](https://github.com/huggingface/optimum):特定のハードウェアデバイス向けに最適化された🤗 Transformersの拡張。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/agent.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/agent.md
new file mode 100644
index 0000000000000000000000000000000000000000..cb7f5a992427500724a6ee00150a87ced8a823d4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/agent.md
@@ -0,0 +1,26 @@
+
+
+# エージェントとツール
+
+
+
+The Agents framework has significantly changed in version v4.41.0.
+This document has been removed as it was referencing an older API.
+
+We eagerly welcome new contributions for the updated API.
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/callback.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/callback.md
new file mode 100644
index 0000000000000000000000000000000000000000..a90044b6cd3769d89cc6fe1898041510d539f6e1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/callback.md
@@ -0,0 +1,135 @@
+
+
+
+# コールバック数
+
+コールバックは、PyTorch のトレーニング ループの動作をカスタマイズできるオブジェクトです。
+トレーニング ループを検査できる [`Trainer`] (この機能は TensorFlow にはまだ実装されていません)
+状態を確認し (進捗レポート、TensorBoard または他の ML プラットフォームへのログ記録など)、決定を下します (初期段階など)。
+停止中)。
+
+コールバックは、返される [`TrainerControl`] オブジェクトを除けば、「読み取り専用」のコード部分です。
+トレーニング ループ内では何も変更できません。トレーニング ループの変更が必要なカスタマイズの場合は、次のことを行う必要があります。
+[`Trainer`] をサブクラス化し、必要なメソッドをオーバーライドします (例については、[trainer](trainer) を参照してください)。
+
+デフォルトでは、`TrainingArguments.report_to` は `"all"` に設定されているため、[`Trainer`] は次のコールバックを使用します。
+
+- [`DefaultFlowCallback`] は、ログ記録、保存、評価のデフォルトの動作を処理します。
+- [`PrinterCallback`] または [`ProgressCallback`] で進行状況を表示し、
+ ログ (最初のログは、[`TrainingArguments`] を通じて tqdm を非アクティブ化する場合に使用され、そうでない場合に使用されます)
+ 2番目です)。
+- [`~integrations.TensorBoardCallback`] (PyTorch >= 1.4 を介して) tensorboard にアクセスできる場合
+ またはテンソルボードX)。
+- [`~integrations.WandbCallback`] [wandb](https://www.wandb.com/) がインストールされている場合。
+- [`~integrations.CometCallback`] [comet_ml](https://www.comet.com/site/) がインストールされている場合。
+- [mlflow](https://www.mlflow.org/) がインストールされている場合は [`~integrations.MLflowCallback`]。
+- [`~integrations.NeptuneCallback`] [neptune](https://neptune.ai/) がインストールされている場合。
+- [`~integrations.AzureMLCallback`] [azureml-sdk](https://pypi.org/project/azureml-sdk/) の場合
+ インストールされています。
+- [`~integrations.CodeCarbonCallback`] [codecarbon](https://pypi.org/project/codecarbon/) の場合
+ インストールされています。
+- [`~integrations.ClearMLCallback`] [clearml](https://github.com/allegroai/clearml) がインストールされている場合。
+- [`~integrations.DagsHubCallback`] [dagshub](https://dagshub.com/) がインストールされている場合。
+- [`~integrations.FlyteCallback`] [flyte](https://flyte.org/) がインストールされている場合。
+- [`~integrations.DVCLiveCallback`] [dvclive](https://www.dvc.org/doc/dvclive) がインストールされている場合。
+
+パッケージがインストールされているが、付随する統合を使用したくない場合は、`TrainingArguments.report_to` を、使用したい統合のみのリストに変更できます (例: `["azure_ml", "wandb"]`) 。
+
+コールバックを実装するメインクラスは [`TrainerCallback`] です。それは、
+[`TrainingArguments`] は [`Trainer`] をインスタンス化するために使用され、それにアクセスできます。
+[`TrainerState`] を介してトレーナーの内部状態を取得し、トレーニング ループ上でいくつかのアクションを実行できます。
+[`TrainerControl`]。
+
+## 利用可能なコールバック
+
+ライブラリで利用可能な [`TrainerCallback`] のリストは次のとおりです。
+
+[[autodoc]] integrations.CometCallback
+ - setup
+
+[[autodoc]] DefaultFlowCallback
+
+[[autodoc]] PrinterCallback
+
+[[autodoc]] ProgressCallback
+
+[[autodoc]] EarlyStoppingCallback
+
+[[autodoc]] integrations.TensorBoardCallback
+
+[[autodoc]] integrations.WandbCallback
+ - setup
+
+[[autodoc]] integrations.MLflowCallback
+ - setup
+
+[[autodoc]] integrations.AzureMLCallback
+
+[[autodoc]] integrations.CodeCarbonCallback
+
+[[autodoc]] integrations.NeptuneCallback
+
+[[autodoc]] integrations.ClearMLCallback
+
+[[autodoc]] integrations.DagsHubCallback
+
+[[autodoc]] integrations.FlyteCallback
+
+[[autodoc]] integrations.DVCLiveCallback
+ - setup
+
+## TrainerCallback
+
+[[autodoc]] TrainerCallback
+
+以下は、カスタム コールバックを PyTorch [`Trainer`] に登録する方法の例です。
+
+```python
+class MyCallback(TrainerCallback):
+ "A callback that prints a message at the beginning of training"
+
+ def on_train_begin(self, args, state, control, **kwargs):
+ print("Starting training")
+
+
+trainer = Trainer(
+ model,
+ args,
+ train_dataset=train_dataset,
+ eval_dataset=eval_dataset,
+ callbacks=[MyCallback], # We can either pass the callback class this way or an instance of it (MyCallback())
+)
+```
+
+コールバックを登録する別の方法は、次のように `trainer.add_callback()` を呼び出すことです。
+
+```python
+trainer = Trainer(...)
+trainer.add_callback(MyCallback)
+# Alternatively, we can pass an instance of the callback class
+trainer.add_callback(MyCallback())
+```
+
+## TrainerState
+
+[[autodoc]] TrainerState
+
+## TrainerControl
+
+[[autodoc]] TrainerControl
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/configuration.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/configuration.md
new file mode 100644
index 0000000000000000000000000000000000000000..7fab5269e2049f61c8c83859a19b218d247cebb5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/configuration.md
@@ -0,0 +1,31 @@
+
+
+# 構成
+
+基本クラス [`PretrainedConfig`] は、設定をロード/保存するための一般的なメソッドを実装します。
+ローカル ファイルまたはディレクトリから、またはライブラリ (ダウンロードされた) によって提供される事前トレーニング済みモデル構成から
+HuggingFace の AWS S3 リポジトリから)。
+
+各派生構成クラスはモデル固有の属性を実装します。すべての構成クラスに存在する共通の属性は次のとおりです。
+`hidden_size`、`num_attention_heads`、および `num_hidden_layers`。テキスト モデルはさらに以下を実装します。
+`vocab_size`。
+
+## PretrainedConfig
+
+[[autodoc]] PretrainedConfig
+ - push_to_hub
+ - all
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/data_collator.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/data_collator.md
new file mode 100644
index 0000000000000000000000000000000000000000..c37f1aeef4d1ccb17446da900b39904b92d1d68b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/data_collator.md
@@ -0,0 +1,67 @@
+
+
+# データ照合者
+
+データ照合器は、データセット要素のリストを入力として使用してバッチを形成するオブジェクトです。これらの要素は、
+`train_dataset` または `eval_dataset` の要素と同じ型。
+
+バッチを構築できるようにするために、データ照合者は何らかの処理 (パディングなど) を適用する場合があります。そのうちのいくつかは(
+[`DataCollatorForLanguageModeling`]) ランダムなデータ拡張 (ランダム マスキングなど) も適用します
+形成されたバッチ上で。
+
+使用例は、[サンプル スクリプト](../examples) または [サンプル ノートブック](../notebooks) にあります。
+
+## Default data collator
+
+[[autodoc]] data.data_collator.default_data_collator
+
+## DefaultDataCollator
+
+[[autodoc]] data.data_collator.DefaultDataCollator
+
+## DataCollatorWithPadding
+
+[[autodoc]] data.data_collator.DataCollatorWithPadding
+
+## DataCollatorForTokenClassification
+
+[[autodoc]] data.data_collator.DataCollatorForTokenClassification
+
+## DataCollatorForSeq2Seq
+
+[[autodoc]] data.data_collator.DataCollatorForSeq2Seq
+
+## DataCollatorForLanguageModeling
+
+[[autodoc]] data.data_collator.DataCollatorForLanguageModeling
+ - numpy_mask_tokens
+ - tf_mask_tokens
+ - torch_mask_tokens
+
+## DataCollatorForWholeWordMask
+
+[[autodoc]] data.data_collator.DataCollatorForWholeWordMask
+ - numpy_mask_tokens
+ - tf_mask_tokens
+ - torch_mask_tokens
+
+## DataCollatorForPermutationLanguageModeling
+
+[[autodoc]] data.data_collator.DataCollatorForPermutationLanguageModeling
+ - numpy_mask_tokens
+ - tf_mask_tokens
+ - torch_mask_tokens
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/deepspeed.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/deepspeed.md
new file mode 100644
index 0000000000000000000000000000000000000000..4406ce4a34e21e3ed8287fb3bd071890dcdc070c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/deepspeed.md
@@ -0,0 +1,2254 @@
+
+
+# DeepSpeed Integration
+
+[DeepSpeed](https://github.com/microsoft/DeepSpeed) は、[ZeRO 論文](https://arxiv.org/abs/1910.02054) で説明されているすべてを実装します。現在、次のものを完全にサポートしています。
+
+1. オプティマイザーの状態分割 (ZeRO ステージ 1)
+2. 勾配分割 (ZeRO ステージ 2)
+3. パラメーターの分割 (ZeRO ステージ 3)
+4. カスタム混合精度トレーニング処理
+5. 一連の高速 CUDA 拡張ベースのオプティマイザー
+6. CPU および NVMe への ZeRO オフロード
+
+ZeRO-Offload には独自の専用ペーパーがあります: [ZeRO-Offload: Democratizing Billion-Scale Model Training](https://arxiv.org/abs/2101.06840)。 NVMe サポートについては、論文 [ZeRO-Infinity: Breaking the GPU Memory Wall for Extreme Scale Deep Learning](https://arxiv.org/abs/2104.07857)。
+
+DeepSpeed ZeRO-2 は、その機能が推論には役に立たないため、主にトレーニングのみに使用されます。
+
+DeepSpeed ZeRO-3 は、巨大なモデルを複数の GPU にロードできるため、推論にも使用できます。
+単一の GPU では不可能です。
+
+🤗 Transformers は、2 つのオプションを介して [DeepSpeed](https://github.com/microsoft/DeepSpeed) を統合します。
+
+1. [`Trainer`] によるコア DeepSpeed 機能の統合。何でもやってくれるタイプです
+ 統合の場合 - カスタム構成ファイルを指定するか、テンプレートを使用するだけで、他に何もする必要はありません。たいていの
+ このドキュメントではこの機能に焦点を当てています。
+2. [`Trainer`] を使用せず、DeepSpeed を統合した独自のトレーナーを使用したい場合
+ `from_pretrained` や `from_config` などのコア機能には、重要な機能の統合が含まれています。
+ ZeRO ステージ 3 以降の `zero.Init`などの DeepSpeed の部分。この機能を活用するには、次のドキュメントをお読みください。
+ [非トレーナー DeepSpeed 統合](#nontrainer-deepspeed-integration)。
+
+統合されているもの:
+
+トレーニング:
+
+1. DeepSpeed ZeRO トレーニングは、ZeRO-Infinity (CPU および NVME オフロード) を使用して完全な ZeRO ステージ 1、2、および 3 をサポートします。
+
+推論:
+
+1. DeepSpeed ZeRO Inference は、ZeRO-Infinity による ZeRO ステージ 3 をサポートします。トレーニングと同じ ZeRO プロトコルを使用しますが、
+ オプティマイザと lr スケジューラは使用せず、ステージ 3 のみが関連します。詳細については、以下を参照してください。
+ [ゼロ推論](#zero-inference)。
+
+DeepSpeed Inference もあります。これは、Tensor Parallelism の代わりに Tensor Parallelism を使用するまったく異なるテクノロジーです。
+ZeRO (近日公開)。
+
+ --deepspeed ds_config.json
+```
+
+または、`deepspeed`によって提供されるランチャーを使用します。
+
+```bash
+deepspeed --num_gpus=2 your_program.py --deepspeed ds_config.json
+```
+
+ご覧のとおり、引数は同じではありませんが、ほとんどのニーズではどちらでも機能します。の
+さまざまなノードと GPU を構成する方法の詳細については、[こちら](https://www.deepspeed.ai/getting-started/#resource-configuration-multi-node) を参照してください。
+
+`deepspeed`ランチャーを使用し、利用可能なすべての GPU を使用したい場合は、`--num_gpus`フラグを省略するだけです。
+
+以下は、利用可能なすべての GPU をデプロイする DeepSpeed で`run_translation.py`を実行する例です。
+
+```bash
+deepspeed examples/pytorch/translation/run_translation.py \
+--deepspeed tests/deepspeed/ds_config_zero3.json \
+--model_name_or_path google-t5/t5-small --per_device_train_batch_size 1 \
+--output_dir output_dir --overwrite_output_dir --fp16 \
+--do_train --max_train_samples 500 --num_train_epochs 1 \
+--dataset_name wmt16 --dataset_config "ro-en" \
+--source_lang en --target_lang ro
+```
+
+DeepSpeed のドキュメントには、`--deepspeed --deepspeed_config ds_config.json`が表示される可能性が高いことに注意してください。
+DeepSpeed 関連の引数が 2 つありますが、簡単にするためであり、処理すべき引数がすでに非常に多いためです。
+この 2 つを 1 つの引数に結合しました。
+
+実際の使用例については、この [投稿](https://github.com/huggingface/transformers/issues/8771#issuecomment-759248400) を参照してください。
+
+ --deepspeed ds_config.json
+```
+
+各ノードに SSH で接続し、それぞれのノードで同じコマンドを実行する必要があります。急ぐ必要はありません。ランチャーは両方のノードが同期するまで待機します。
+
+詳細については、[torchrun](https://pytorch.org/docs/stable/elastic/run.html) を参照してください。ちなみに、これは pytorch の数バージョン前の`torch.distributed.launch`を置き換えたランチャーでもあります。
+
+#### ディープスピード ランチャー
+
+代わりに`deepspeed`ランチャーを使用するには、まず`hostfile`ファイルを作成する必要があります。
+
+```
+hostname1 slots=8
+hostname2 slots=8
+```
+
+そして、次のように起動できます。
+
+```bash
+deepspeed --num_gpus 8 --num_nodes 2 --hostfile hostfile --master_addr hostname1 --master_port=9901 \
+your_program.py --deepspeed ds_config.json
+```
+
+`torch.distributed.run`ランチャーとは異なり、`deepspeed`は両方のノードでこのコマンドを自動的に起動します。
+
+詳細については、[リソース構成 (マルチノード)](https://www.deepspeed.ai/getting-started/#resource-configuration-multi-node) を参照してください。
+
+#### Launching in a SLURM environment
+
+SLURM 環境では、次のアプローチを使用できます。以下は、特定の SLURM 環境に適合させるために必要な slurm スクリプト `launch.slurm` です。
+
+```bash
+#SBATCH --job-name=test-nodes # name
+#SBATCH --nodes=2 # nodes
+#SBATCH --ntasks-per-node=1 # crucial - only 1 task per dist per node!
+#SBATCH --cpus-per-task=10 # number of cores per tasks
+#SBATCH --gres=gpu:8 # number of gpus
+#SBATCH --time 20:00:00 # maximum execution time (HH:MM:SS)
+#SBATCH --output=%x-%j.out # output file name
+
+export GPUS_PER_NODE=8
+export MASTER_ADDR=$(scontrol show hostnames $SLURM_JOB_NODELIST | head -n 1)
+export MASTER_PORT=9901
+
+srun --jobid $SLURM_JOBID bash -c 'python -m torch.distributed.run \
+ --nproc_per_node $GPUS_PER_NODE --nnodes $SLURM_NNODES --node_rank $SLURM_PROCID \
+ --master_addr $MASTER_ADDR --master_port $MASTER_PORT \
+your_program.py --deepspeed ds_config.json'
+```
+
+あとは実行をスケジュールするだけです。
+```bash
+sbatch launch.slurm
+```
+
+#### Use of Non-shared filesystem
+
+デフォルトでは、DeepSpeed はマルチノード環境が共有ストレージを使用することを想定しています。これが当てはまらず、各ノードがローカル ファイルシステムしか参照できない場合は、設定ファイルを調整して [`checkpoint`_section](https://www.deepspeed.ai/docs/config-json/#) を含める必要があります。チェックポイント オプション) を次の設定で指定します。
+
+
+```json
+{
+ "checkpoint": {
+ "use_node_local_storage": true
+ }
+}
+```
+
+あるいは、[`Trainer`] の `--save_on_each_node` 引数を使用することもでき、上記の設定は自動的に追加されます。
+
+
+
+このセクションは必読です
+
+
+
+[`Trainer`] と DeepSpeed の両方が正しく機能するには、いくつかの設定値が必要です。
+したがって、検出が困難なエラーにつながる可能性のある定義の競合を防ぐために、それらを構成することにしました。
+[`Trainer`] コマンドライン引数経由。
+
+さらに、一部の構成値はモデルの構成に基づいて自動的に導出されます。
+複数の値を手動で調整することを忘れないでください。[`Trainer`] に大部分を任せるのが最善です
+の設定を行います。
+
+したがって、このガイドの残りの部分では、特別な設定値 `auto` が表示されます。これを設定すると、
+正しい値または最も効率的な値に自動的に置き換えられます。これを無視することを自由に選択してください
+推奨事項を参照し、値を明示的に設定します。この場合、次の点に十分注意してください。
+[`Trainer`] 引数と DeepSpeed 設定は一致します。たとえば、同じものを使用していますか
+学習率、バッチサイズ、または勾配累積設定?これらが一致しない場合、トレーニングは非常に失敗する可能性があります
+方法を検出するのが難しい。あなたは警告を受けました。
+
+DeepSpeed のみに固有の値や、それに合わせて手動で設定する必要がある値が他にも複数あります。
+あなたの要望。
+
+独自のプログラムで、DeepSpeed 構成をマスターとして変更したい場合は、次のアプローチを使用することもできます。
+それに基づいて [`TrainingArguments`] を設定します。手順は次のとおりです。
+
+1. マスター構成として使用する DeepSpeed 構成を作成またはロードします
+2. これらの値に基づいて [`TrainingArguments`] オブジェクトを作成します
+
+`scheduler.params.total_num_steps`などの一部の値は次のように計算されることに注意してください。
+`train` 中に [`Trainer`] を実行しますが、もちろん自分で計算することもできます。
+
+
+
+`deepspeed==0.6.0`の時点では、bf16 サポートは新しく実験的なものです。
+
+bf16 が有効な状態で [勾配累積](#gradient-accumulation) を使用する場合は、bf16 で勾配が累積されることに注意する必要があります。この形式の精度が低いため、これは希望どおりではない可能性があります。損失のある蓄積につながります。
+
+この問題を修正し、より高精度の `dtype` (fp16 または fp32) を使用するオプションを提供するための作業が行われています。
+
+
+
+
+### NCCL Collectives
+
+訓練体制の`dtype`があり、さまざまな削減や収集/分散操作などのコミュニケーション集合体に使用される別の`dtype`があります。
+
+すべての収集/分散操作は、データが含まれているのと同じ `dtype` で実行されるため、bf16 トレーニング体制を使用している場合、データは bf16 で収集されます。収集は損失のない操作です。
+
+さまざまなリデュース操作は非常に損失が大きい可能性があります。たとえば、複数の GPU 間で勾配が平均化される場合、通信が fp16 または bf16 で行われる場合、結果は損失が多くなる可能性があります。複数の数値を低精度でアドバタイズすると結果は正確ではないためです。 。 bf16 では fp16 よりも精度が低いため、さらにそうです。通常は非常に小さい grad を平均する際の損失が最小限に抑えられるため、fp16 で十分であることがよくあります。したがって、デフォルトでは、半精度トレーニングでは fp16 がリダクション演算のデフォルトとして使用されます。ただし、この機能を完全に制御でき、必要に応じて小さなオーバーヘッドを追加して、リダクションが累積 dtype として fp32 を使用し、結果の準備ができた場合にのみ半精度 `dtype` にダウンキャストするようにすることもできます。でトレーニング中です。
+
+デフォルトをオーバーライドするには、新しい構成エントリを追加するだけです。
+
+```json
+{
+ "communication_data_type": "fp32"
+}
+```
+
+この記事の執筆時点での有効な値は、"fp16"、"bfp16"、"fp32"です。
+
+注: ステージ ゼロ 3 には、bf16 通信タイプに関するバグがあり、`deepspeed==0.8.1`で修正されました。
+
+### apex
+
+apex AMP のようなモード セットを設定するには:
+
+```json
+"amp": {
+ "enabled": "auto",
+ "opt_level": "auto"
+}
+```
+
+[`Trainer`] は `args.fp16_backend` の値に基づいて自動的に設定します。
+`args.fp16_opt_level`。
+
+このモードは、`--fp16 --fp16_backend apex --fp16_opt_level 01`コマンド ライン引数が渡されると有効になります。
+
+このモードを明示的に構成することもできます。
+
+```json
+{
+ "amp": {
+ "enabled": true,
+ "opt_level": "O1"
+ }
+}
+```
+
+ただし、[`Trainer`] コマンドライン引数と DeepSpeed を自分で同期することになります。
+構成。
+
+これは[ドキュメント](https://www.deepspeed.ai/docs/config-json/#automatic-mixed-precision-amp-training-options)です。
+
+
+
+`load_state_dict_from_zero_checkpoint` が実行されると、`model` はもはや使用できなくなることに注意してください。
+同じアプリケーションの DeepSpeed コンテキスト。つまり、deepspeed エンジンを再初期化する必要があります。
+`model.load_state_dict(state_dict)` はそこからすべての DeepSpeed マジックを削除します。したがって、これは最後にのみ実行してください
+トレーニングの様子。
+
+
+
+
+もちろん、class:*~transformers.Trainer* を使用する必要はなく、上記の例を独自のものに調整することができます。
+トレーナー。
+
+何らかの理由でさらに改良したい場合は、重みの fp32 `state_dict` を抽出して適用することもできます。
+次の例に示すように、これらは自分で作成します。
+
+```python
+from deepspeed.utils.zero_to_fp32 import get_fp32_state_dict_from_zero_checkpoint
+
+state_dict = get_fp32_state_dict_from_zero_checkpoint(checkpoint_dir) # already on cpu
+model = model.cpu()
+model.load_state_dict(state_dict)
+```
+
+**オフライン FP32 ウェイト リカバリ:**
+
+DeepSpeed は特別な変換スクリプト`zero_to_fp32.py`を作成し、チェックポイントの最上位に配置します。
+フォルダ。このスクリプトを使用すると、いつでも重みを抽出できます。スクリプトはスタンドアロンなので、もう必要ありません。
+抽出を行うための設定ファイルまたは `Trainer` が必要です。
+
+チェックポイント フォルダーが次のようになっているとします。
+
+```bash
+$ ls -l output_dir/checkpoint-1/
+-rw-rw-r-- 1 stas stas 1.4K Mar 27 20:42 config.json
+drwxrwxr-x 2 stas stas 4.0K Mar 25 19:52 global_step1/
+-rw-rw-r-- 1 stas stas 12 Mar 27 13:16 latest
+-rw-rw-r-- 1 stas stas 827K Mar 27 20:42 optimizer.pt
+-rw-rw-r-- 1 stas stas 231M Mar 27 20:42 pytorch_model.bin
+-rw-rw-r-- 1 stas stas 623 Mar 27 20:42 scheduler.pt
+-rw-rw-r-- 1 stas stas 1.8K Mar 27 20:42 special_tokens_map.json
+-rw-rw-r-- 1 stas stas 774K Mar 27 20:42 spiece.model
+-rw-rw-r-- 1 stas stas 1.9K Mar 27 20:42 tokenizer_config.json
+-rw-rw-r-- 1 stas stas 339 Mar 27 20:42 trainer_state.json
+-rw-rw-r-- 1 stas stas 2.3K Mar 27 20:42 training_args.bin
+-rwxrw-r-- 1 stas stas 5.5K Mar 27 13:16 zero_to_fp32.py*
+```
+
+この例では、DeepSpeed チェックポイント サブフォルダー *global_step1* が 1 つだけあります。したがって、FP32を再構築するには
+重みを実行するだけです:
+
+```bash
+python zero_to_fp32.py . pytorch_model.bin
+```
+
+これだよ。 `pytorch_model.bin`には、複数の GPU から統合された完全な fp32 モデルの重みが含まれるようになります。
+
+スクリプトは、ZeRO-2 または ZeRO-3 チェックポイントを自動的に処理できるようになります。
+
+`python zero_to_fp32.py -h` を実行すると、使用方法の詳細が表示されます。
+
+スクリプトは、ファイル`latest`の内容を使用して deepspeed サブフォルダーを自動検出します。
+例には`global_step1`が含まれます。
+
+注: 現在、スクリプトには最終的な fp32 モデルの重みの 2 倍の一般 RAM が必要です。
+
+### ZeRO-3 と Infinity Nuances
+
+ZeRO-3 は、パラメータ シャーディング機能の点で ZeRO-2 とは大きく異なります。
+
+ZeRO-Infinity は ZeRO-3 をさらに拡張し、NVMe メモリやその他の複数の速度とスケーラビリティの向上をサポートします。
+
+モデルに特別な変更を加える必要がなくても正常に動作するようにあらゆる努力が払われてきましたが、特定の点では
+状況によっては、次の情報が必要になる場合があります。
+
+#### Constructing Massive Models
+
+
+DeepSpeed/ZeRO-3 は、既存の RAM に収まらない可能性のある数兆のパラメータを持つモデルを処理できます。そのような場合、
+また、初期化をより高速に実行したい場合は、*deepspeed.zero.Init()* を使用してモデルを初期化します。
+コンテキスト マネージャー (関数デコレーターでもあります)。次のようになります。
+
+```python
+from transformers import T5ForConditionalGeneration, T5Config
+import deepspeed
+
+with deepspeed.zero.Init():
+ config = T5Config.from_pretrained("google-t5/t5-small")
+ model = T5ForConditionalGeneration(config)
+```
+
+ご覧のとおり、これによりランダムに初期化されたモデルが得られます。
+
+事前トレーニングされたモデルを使用したい場合、`model_class.from_pretrained` は次の条件を満たす限りこの機能を有効にします。
+`is_deepspeed_zero3_enabled()` は `True` を返します。これは現在、
+[`TrainingArguments`] オブジェクト (渡された DeepSpeed 構成ファイルに ZeRO-3 構成が含まれている場合)
+セクション。したがって、呼び出しの前に** [`TrainingArguments`] オブジェクトを作成する必要があります。
+`from_pretrained`。考えられるシーケンスの例を次に示します。
+
+```python
+from transformers import AutoModel, Trainer, TrainingArguments
+
+training_args = TrainingArguments(..., deepspeed=ds_config)
+model = AutoModel.from_pretrained("google-t5/t5-small")
+trainer = Trainer(model=model, args=training_args, ...)
+```
+
+公式のサンプル スクリプトを使用していて、コマンド ライン引数に `--deepspeed ds_config.json` が含まれている場合
+ZeRO-3 設定を有効にすると、これがサンプル スクリプトの記述方法であるため、すべてがすでに完了しています。
+
+注: モデルの fp16 重みが単一の GPU のメモリに収まらない場合は、この機能を使用する必要があります。
+
+この方法とその他の関連機能の詳細については、[大規模モデルの構築](https://deepspeed.readthedocs.io/en/latest/zero3.html#constructing-massive-models) を参照してください。
+
+また、fp16 で事前訓練されたモデルをロードするときは、`from_pretrained` に使用するように指示する必要があります。
+`torch_dtype=torch.float16`。詳細については、[from_pretrained-torch-dtype](#from_pretrained-torch-dtype) を参照してください。
+
+#### Gathering Parameters
+
+複数の GPU 上の ZeRO-3 では、現在の GPU のパラメータでない限り、単一の GPU がすべてのパラメータを持つことはありません。
+実行層。したがって、すべてのレイヤーのすべてのパラメーターに一度にアクセスする必要がある場合は、それを行うための特定の方法があります。
+ほとんどの場合は必要ありませんが、必要な場合は、[パラメータの収集](https://deepspeed.readthedocs.io/en/latest/zero3.html#manual-parameter-coordination) を参照してください。
+
+ただし、いくつかの場所で内部的に使用しています。その例の 1 つは、事前トレーニングされたモデルの重みをロードするときです。
+`from_pretrained`。一度に 1 つのレイヤーをロードし、参加しているすべての GPU に即座に分割します。
+大規模なモデルでは、メモリの関係で、1 つの GPU にロードしてから複数の GPU に分散することはできません。
+制限。
+
+また、ZeRO-3 では、独自のコードを作成し、次のようなモデル パラメーターの重みが発生するとします。
+
+```python
+tensor([1.0], device="cuda:0", dtype=torch.float16, requires_grad=True)
+```
+
+`tensor([1.])` にストレスを感じた場合、またはパラメータのサイズが `1` であるというエラーが発生した場合
+より大きな多次元形状。これは、パラメーターが分割されており、表示されるのは ZeRO-3 プレースホルダーであることを意味します。
+
+ --do_eval --deepspeed ds_config.json
+```
+
+唯一重要なことは、ZeRO-2 には何の利点もないため、ZeRO-3 構成を使用する必要があるということです。
+ZeRO-3 のみがパラメーターのシャーディングを実行するのに対し、ZeRO-1 は勾配とオプティマイザーの状態をシャーディングするため、推論に役立ちます。
+
+以下は、利用可能なすべての GPU をデプロイする DeepSpeed で`run_translation.py`を実行する例です。
+
+
+```bash
+deepspeed examples/pytorch/translation/run_translation.py \
+--deepspeed tests/deepspeed/ds_config_zero3.json \
+--model_name_or_path google-t5/t5-small --output_dir output_dir \
+--do_eval --max_eval_samples 50 --warmup_steps 50 \
+--max_source_length 128 --val_max_target_length 128 \
+--overwrite_output_dir --per_device_eval_batch_size 4 \
+--predict_with_generate --dataset_config "ro-en" --fp16 \
+--source_lang en --target_lang ro --dataset_name wmt16 \
+--source_prefix "translate English to Romanian: "
+```
+
+推論のために、オプティマイザーの状態と勾配によって使用される追加の大きなメモリは必要ないため、
+はるかに大きなバッチやシーケンス長を同じハードウェアに適合できる必要があります。
+
+さらに、DeepSpeed は現在、Deepspeed-Inference と呼ばれる関連製品を開発していますが、これとは何の関係もありません。
+ZeRO テクノロジーに準拠していますが、代わりにテンソル並列処理を使用して、単一の GPU に収まらないモデルをスケーリングします。これは
+現在開発中です。製品が完成したら統合を提供する予定です。
+
+
+### Memory Requirements
+
+Deepspeed ZeRO はメモリを CPU (および NVMe) にオフロードできるため、フレームワークは、使用されている GPU の数に応じて必要な CPU および GPU メモリの量を知ることができるユーティリティを提供します。
+
+単一の GPU で `bigscience/T0_3B`を微調整するために必要なメモリの量を見積もってみましょう。
+
+```bash
+$ python -c 'from transformers import AutoModel; \
+from deepspeed.runtime.zero.stage3 import estimate_zero3_model_states_mem_needs_all_live; \
+model = AutoModel.from_pretrained("bigscience/T0_3B"); \
+estimate_zero3_model_states_mem_needs_all_live(model, num_gpus_per_node=1, num_nodes=1)'
+[...]
+Estimated memory needed for params, optim states and gradients for a:
+HW: Setup with 1 node, 1 GPU per node.
+SW: Model with 2783M total params, 65M largest layer params.
+ per CPU | per GPU | Options
+ 70.00GB | 0.25GB | offload_param=cpu , offload_optimizer=cpu , zero_init=1
+ 70.00GB | 0.25GB | offload_param=cpu , offload_optimizer=cpu , zero_init=0
+ 62.23GB | 5.43GB | offload_param=none, offload_optimizer=cpu , zero_init=1
+ 62.23GB | 5.43GB | offload_param=none, offload_optimizer=cpu , zero_init=0
+ 0.37GB | 46.91GB | offload_param=none, offload_optimizer=none, zero_init=1
+ 15.56GB | 46.91GB | offload_param=none, offload_optimizer=none, zero_init=0
+```
+
+したがって、単一の 80 GB GPU で CPU オフロードなしで搭載することも、小さな 8 GB GPU でも最大 60 GB の CPU メモリが必要になることも可能です。 (これはパラメータ、オプティマイザの状態、および勾配のためのメモリであることに注意してください。cuda カーネル、アクティベーション、および一時メモリにはもう少し多くのメモリが必要です。)
+
+次に、コストと速度のトレードオフになります。より小さい GPU を購入またはレンタルした方が安くなります (Deepspeed ZeRO では複数の GPU を使用できるため、GPU の数を減らすこともできます)。しかし、その場合は遅くなります。そのため、何かを実行する速度を気にしなくても、速度の低下は GPU の使用時間に直接影響し、コストが増大するため、どれが最も効果的かを実験して比較してください。
+
+十分な GPU メモリがある場合は、すべてが高速になるため、CPU/NVMe オフロードを必ず無効にしてください。
+
+たとえば、2 つの GPU に対して同じことを繰り返してみましょう。
+
+```bash
+$ python -c 'from transformers import AutoModel; \
+from deepspeed.runtime.zero.stage3 import estimate_zero3_model_states_mem_needs_all_live; \
+model = AutoModel.from_pretrained("bigscience/T0_3B"); \
+estimate_zero3_model_states_mem_needs_all_live(model, num_gpus_per_node=2, num_nodes=1)'
+[...]
+Estimated memory needed for params, optim states and gradients for a:
+HW: Setup with 1 node, 2 GPUs per node.
+SW: Model with 2783M total params, 65M largest layer params.
+ per CPU | per GPU | Options
+ 70.00GB | 0.25GB | offload_param=cpu , offload_optimizer=cpu , zero_init=1
+ 70.00GB | 0.25GB | offload_param=cpu , offload_optimizer=cpu , zero_init=0
+ 62.23GB | 2.84GB | offload_param=none, offload_optimizer=cpu , zero_init=1
+ 62.23GB | 2.84GB | offload_param=none, offload_optimizer=cpu , zero_init=0
+ 0.74GB | 23.58GB | offload_param=none, offload_optimizer=none, zero_init=1
+ 31.11GB | 23.58GB | offload_param=none, offload_optimizer=none, zero_init=0
+
+```
+
+したがって、ここでは、CPU にオフロードせずに 2x 32GB 以上の GPU が必要になります。
+
+詳細については、[メモリ推定ツール](https://deepspeed.readthedocs.io/en/latest/memory.html) を参照してください。
+
+
+### Filing Issues
+
+
+ここでは、問題の真相をすぐに解明し、作業のブロックを解除できるよう、問題を報告する方法を説明します。
+
+レポートには必ず次の内容を含めてください。
+
+1. レポート内の完全な Deepspeed 構成ファイル
+
+2. [`Trainer`] を使用している場合はコマンドライン引数、または
+ トレーナーのセットアップを自分でスクリプト作成している場合は、[`TrainingArguments`] 引数。しないでください
+ [`TrainingArguments`] には無関係なエントリが多数含まれているため、ダンプします。
+
+3. 次の出力:
+
+ ```bash
+ python -c 'import torch; print(f"torch: {torch.__version__}")'
+ python -c 'import transformers; print(f"transformers: {transformers.__version__}")'
+ python -c 'import deepspeed; print(f"deepspeed: {deepspeed.__version__}")'
+ ```
+
+4. 可能であれば、問題を再現できる Google Colab ノートブックへのリンクを含めてください。これを使えます
+ [ノートブック](https://github.com/stas00/porting/blob/master/transformers/deepspeed/DeepSpeed_on_colab_CLI.ipynb) として
+ 出発点。
+
+5. 不可能でない限り、カスタムデータセットではなく、常に使用できる標準データセットを使用してください。
+
+6. 可能であれば、既存の [サンプル](https://github.com/huggingface/transformers/tree/main/examples/pytorch) のいずれかを使用して問題を再現してみてください。
+
+- Deepspeed が問題の原因ではないことがよくあります。
+
+ 提出された問題の一部は、Deepspeed とは無関係であることが判明しました。それは、Deepspeed がセットアップから削除された後です。
+ 問題はまだ残っていた。
+
+ したがって、完全に明白でない場合は、DeepSpeed 関連の問題です。
+ 例外が発生し、DeepSpeed モジュールが関係していることがわかります。まず、DeepSpeed を含まないセットアップを再テストしてください。
+ 問題が解決しない場合にのみ、Deepspeed について言及し、必要な詳細をすべて提供してください。
+
+- 問題が統合部分ではなく DeepSpeed コアにあることが明らかな場合は、問題を提出してください。
+ [Deepspeed](https://github.com/microsoft/DeepSpeed/) を直接使用します。よくわからない場合でも、ご安心ください。
+ どちらの問題トラッカーでも問題ありません。投稿されたらそれを判断し、次の場合は別の問題トラッカーにリダイレクトします。
+ そうである必要がある。
+
+
+### Troubleshooting
+
+#### the `deepspeed` process gets killed at startup without a traceback
+
+`deepspeed`プロセスが起動時にトレースバックなしで強制終了された場合、それは通常、プログラムが試行したことを意味します。
+システムが持っているよりも多くの CPU メモリを割り当てるか、プロセスが割り当てを許可されているため、OS カーネルがそれを強制終了します。
+プロセス。これは、設定ファイルに `offload_optimizer` または `offload_param` が含まれている可能性が高いためです。
+どちらも`cpu`にオフロードするように設定されています。 NVMe を使用している場合は、次の環境で実行している場合は NVMe へのオフロードを試してください。
+ゼロ-3。 [特定のモデルに必要なメモリ量を見積もる]方法は次のとおりです(https://deepspeed.readthedocs.io/en/latest/memory.html)。
+
+#### training and/or eval/predict loss is `NaN`
+
+これは、bf16 混合精度モードで事前トレーニングされたモデルを取得し、それを fp16 (混合精度の有無にかかわらず) で使用しようとした場合によく発生します。 TPU でトレーニングされたほとんどのモデル、および多くの場合、Google によってリリースされたモデルは、このカテゴリに分類されます (たとえば、ほぼすべての t5 ベースのモデル)。ここでの解決策は、ハードウェアがサポートしている場合 (TPU、Ampere GPU 以降)、fp32 または bf16 を使用することです。
+
+```json
+{
+ "fp16": {
+ "enabled": "auto",
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ }
+}
+```
+
+ログには、Deepspeed が次のように`OVERFLOW!`を報告していることがわかります。
+
+```
+0%| | 0/189 [00:00=4.28` 以降、`synced_gpus` が明示的に指定されていない場合、これらの条件が検出されると自動的に `True` に設定されます。ただし、必要に応じて `synced_gpus` の値をオーバーライドすることもできます。
+
+## Deepspeed 統合のテスト
+
+DeepSpeed 統合を含む PR を送信する場合は、CircleCI PR CI セットアップには GPU がないことに注意してください。そのため、GPU を必要とするテストは別の CI で毎晩のみ実行されます。したがって、PR で緑色の CI レポートが表示されても、DeepSpeed テストが合格したことを意味するわけではありません。
+
+DeepSpeed テストを実行するには、少なくとも以下を実行してください。
+
+```bash
+RUN_SLOW=1 pytest tests/deepspeed/test_deepspeed.py
+```
+
+モデリングまたは pytorch サンプル コードのいずれかを変更した場合は、Model Zoo テストも実行します。以下はすべての DeepSpeed テストを実行します。
+
+```bash
+RUN_SLOW=1 pytest tests/deepspeed
+```
+
+
+## Main DeepSpeed Resources
+
+- [プロジェクトの github](https://github.com/microsoft/deepspeed)
+- [使用方法ドキュメント](https://www.deepspeed.ai/getting-started/)
+- [API ドキュメント](https://deepspeed.readthedocs.io/en/latest/index.html)
+- [ブログ投稿](https://www.microsoft.com/en-us/research/search/?q=deepspeed)
+
+論文:
+
+- [ZeRO: 兆パラメータ モデルのトレーニングに向けたメモリの最適化](https://arxiv.org/abs/1910.02054)
+- [ZeRO-Offload: 10 億規模のモデル トレーニングの民主化](https://arxiv.org/abs/2101.06840)
+- [ZeRO-Infinity: 極限スケールの深層学習のための GPU メモリの壁を打ち破る](https://arxiv.org/abs/2104.07857)
+
+最後に、HuggingFace [`Trainer`] は DeepSpeed のみを統合していることを覚えておいてください。
+DeepSpeed の使用に関して問題や質問がある場合は、[DeepSpeed GitHub](https://github.com/microsoft/DeepSpeed/issues) に問題を提出してください。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/feature_extractor.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/feature_extractor.md
new file mode 100644
index 0000000000000000000000000000000000000000..a2bd8c59a84f35f5a2b6bf131bb5eba4ccb2c677
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/feature_extractor.md
@@ -0,0 +1,41 @@
+
+
+# Feature Extractor
+
+
+フィーチャーエクストラクタは、オーディオまたはビジョンモデルのための入力フィーチャーの準備を担当しています。これには、シーケンスからのフィーチャー抽出(例:オーディオファイルの前処理からLog-Melスペクトログラムフィーチャーへの変換)、画像からのフィーチャー抽出(例:画像ファイルのクロッピング)、またパディング、正規化、そしてNumpy、PyTorch、TensorFlowテンソルへの変換も含まれます。
+
+
+## FeatureExtractionMixin
+
+[[autodoc]] feature_extraction_utils.FeatureExtractionMixin
+ - from_pretrained
+ - save_pretrained
+
+## SequenceFeatureExtractor
+
+[[autodoc]] SequenceFeatureExtractor
+ - pad
+
+## BatchFeature
+
+[[autodoc]] BatchFeature
+
+## ImageFeatureExtractionMixin
+
+[[autodoc]] image_utils.ImageFeatureExtractionMixin
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/image_processor.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/image_processor.md
new file mode 100644
index 0000000000000000000000000000000000000000..bfd33b83c2e50b8f41ee0e6584ee512a1be45bbc
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/image_processor.md
@@ -0,0 +1,33 @@
+
+
+# Image Processor
+
+画像プロセッサは、ビジョン モデルの入力特徴の準備とその出力の後処理を担当します。これには、サイズ変更、正規化、PyTorch、TensorFlow、Flax、Numpy テンソルへの変換などの変換が含まれます。ロジットをセグメンテーション マスクに変換するなど、モデル固有の後処理も含まれる場合があります。
+
+## ImageProcessingMixin
+
+[[autodoc]] image_processing_utils.ImageProcessingMixin
+ - from_pretrained
+ - save_pretrained
+
+## BatchFeature
+
+[[autodoc]] BatchFeature
+
+## BaseImageProcessor
+
+[[autodoc]] image_processing_utils.BaseImageProcessor
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/keras_callbacks.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/keras_callbacks.md
new file mode 100644
index 0000000000000000000000000000000000000000..ff28107a4345795ff04e11ffec7f76a93561635a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/keras_callbacks.md
@@ -0,0 +1,28 @@
+
+
+# Keras callbacks
+
+Keras を使用して Transformers モデルをトレーニングする場合、一般的な処理を自動化するために使用できるライブラリ固有のコールバックがいくつかあります。
+タスク:
+
+## KerasMetricCallback
+
+[[autodoc]] KerasMetricCallback
+
+## PushToHubCallback
+
+[[autodoc]] PushToHubCallback
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/logging.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/logging.md
new file mode 100644
index 0000000000000000000000000000000000000000..4b4f4a2a3e0940e353ffa7f08f9bba842cbbfbc3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/logging.md
@@ -0,0 +1,121 @@
+
+
+# Logging
+
+🤗 Transformersには、ライブラリの詳細度を簡単に設定できる中央集中型のロギングシステムがあります。
+
+現在、ライブラリのデフォルトの詳細度は「WARNING」です。
+
+詳細度を変更するには、直接設定メソッドの1つを使用するだけです。例えば、詳細度をINFOレベルに変更する方法は以下の通りです。
+
+
+```python
+import transformers
+
+transformers.logging.set_verbosity_info()
+```
+
+
+環境変数 `TRANSFORMERS_VERBOSITY` を使用して、デフォルトの冗長性をオーバーライドすることもできます。設定できます
+`debug`、`info`、`warning`、`error`、`critical` のいずれかに変更します。例えば:
+
+```bash
+TRANSFORMERS_VERBOSITY=error ./myprogram.py
+```
+
+
+さらに、一部の「警告」は環境変数を設定することで無効にできます。
+`TRANSFORMERS_NO_ADVISORY_WARNINGS` を *1* などの true 値に設定します。これにより、次を使用してログに記録される警告が無効になります。
+[`logger.warning_advice`]。例えば:
+
+```bash
+TRANSFORMERS_NO_ADVISORY_WARNINGS=1 ./myprogram.py
+```
+
+
+以下は、独自のモジュールまたはスクリプトでライブラリと同じロガーを使用する方法の例です。
+
+```python
+from transformers.utils import logging
+
+logging.set_verbosity_info()
+logger = logging.get_logger("transformers")
+logger.info("INFO")
+logger.warning("WARN")
+```
+
+このロギング モジュールのすべてのメソッドは以下に文書化されています。主なメソッドは次のとおりです。
+[`logging.get_verbosity`] ロガーの現在の冗長レベルを取得します。
+[`logging.set_verbosity`] を使用して、冗長性を選択したレベルに設定します。順番に(少ないものから)
+冗長から最も冗長まで)、それらのレベル (括弧内は対応する int 値) は次のとおりです。
+
+- `transformers.logging.CRITICAL` または `transformers.logging.FATAL` (int 値、50): 最も多いもののみをレポートします。
+ 重大なエラー。
+- `transformers.logging.ERROR` (int 値、40): エラーのみを報告します。
+- `transformers.logging.WARNING` または `transformers.logging.WARN` (int 値、30): エラーと
+ 警告。これはライブラリで使用されるデフォルトのレベルです。
+- `transformers.logging.INFO` (int 値、20): エラー、警告、および基本情報をレポートします。
+- `transformers.logging.DEBUG` (int 値、10): すべての情報をレポートします。
+
+デフォルトでは、モデルのダウンロード中に「tqdm」進行状況バーが表示されます。 [`logging.disable_progress_bar`] および [`logging.enable_progress_bar`] を使用して、この動作を抑制または抑制解除できます。
+
+## `logging` vs `warnings`
+
+Python には、よく組み合わせて使用される 2 つのロギング システムがあります。上で説明した `logging` と `warnings` です。
+これにより、特定のバケット内の警告をさらに分類できます (例: 機能またはパスの`FutureWarning`)
+これはすでに非推奨になっており、`DeprecationWarning`は今後の非推奨を示します。
+
+両方とも`transformers`ライブラリで使用します。 `logging`の`captureWarning`メソッドを活用して適応させて、
+これらの警告メッセージは、上記の冗長設定ツールによって管理されます。
+
+それはライブラリの開発者にとって何を意味しますか?次のヒューリスティックを尊重する必要があります。
+- `warnings`は、ライブラリおよび`transformers`に依存するライブラリの開発者に優先されるべきです。
+- `logging`は、日常のプロジェクトでライブラリを使用するライブラリのエンドユーザーに使用する必要があります。
+
+以下の`captureWarnings`メソッドのリファレンスを参照してください。
+
+[[autodoc]] logging.captureWarnings
+
+## Base setters
+
+[[autodoc]] logging.set_verbosity_error
+
+[[autodoc]] logging.set_verbosity_warning
+
+[[autodoc]] logging.set_verbosity_info
+
+[[autodoc]] logging.set_verbosity_debug
+
+## Other functions
+
+[[autodoc]] logging.get_verbosity
+
+[[autodoc]] logging.set_verbosity
+
+[[autodoc]] logging.get_logger
+
+[[autodoc]] logging.enable_default_handler
+
+[[autodoc]] logging.disable_default_handler
+
+[[autodoc]] logging.enable_explicit_format
+
+[[autodoc]] logging.reset_format
+
+[[autodoc]] logging.enable_progress_bar
+
+[[autodoc]] logging.disable_progress_bar
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/model.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/model.md
new file mode 100644
index 0000000000000000000000000000000000000000..916040c4a3b275cf695fed54ce29622636b0d194
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/model.md
@@ -0,0 +1,160 @@
+
+
+# Models
+
+ベースクラスである [`PreTrainedModel`]、[`TFPreTrainedModel`]、[`FlaxPreTrainedModel`] は、モデルの読み込みと保存に関する共通のメソッドを実装しており、これはローカルのファイルやディレクトリから、またはライブラリが提供する事前学習モデル構成(HuggingFaceのAWS S3リポジトリからダウンロード)からモデルを読み込むために使用できます。
+
+[`PreTrainedModel`] と [`TFPreTrainedModel`] は、次の共通のメソッドも実装しています:
+
+- 語彙に新しいトークンが追加された場合に、入力トークン埋め込みのリサイズを行う
+- モデルのアテンションヘッドを刈り込む
+
+各モデルに共通するその他のメソッドは、[`~modeling_utils.ModuleUtilsMixin`](PyTorchモデル用)および[`~modeling_tf_utils.TFModuleUtilsMixin`](TensorFlowモデル用)で定義されており、テキスト生成の場合、[`~generation.GenerationMixin`](PyTorchモデル用)、[`~generation.TFGenerationMixin`](TensorFlowモデル用)、および[`~generation.FlaxGenerationMixin`](Flax/JAXモデル用)もあります。
+
+
+## PreTrainedModel
+
+[[autodoc]] PreTrainedModel
+ - push_to_hub
+ - all
+
+
+
+`output_hidden_states=True`を渡すと、`outputs.hidden_states[-1]`が `outputs.last_hidden_states` と正確に一致することを期待するかもしれない。
+しかし、必ずしもそうなるとは限りません。モデルによっては、最後に隠された状態が返されたときに、正規化やその後の処理を適用するものもあります。
+
+
+
+
+通常と同じように各属性にアクセスできます。その属性がモデルから返されなかった場合は、
+は `None`を取得します。ここで、たとえば`outputs.loss`はモデルによって計算された損失であり、`outputs.attentions`は
+`None`。
+
+`outputs`オブジェクトをタプルとして考える場合、`None`値を持たない属性のみが考慮されます。
+たとえば、ここには 2 つの要素、`loss`、次に`logits`があります。
+
+```python
+outputs[:2]
+```
+
+たとえば、タプル `(outputs.loss, Outputs.logits)` を返します。
+
+`outputs`オブジェクトを辞書として考慮する場合、「None」を持たない属性のみが考慮されます。
+価値観。たとえば、ここには`loss` と `logits`という 2 つのキーがあります。
+
+ここでは、複数のモデル タイプで使用される汎用モデルの出力を文書化します。具体的な出力タイプは次のとおりです。
+対応するモデルのページに記載されています。
+
+## ModelOutput
+
+[[autodoc]] utils.ModelOutput
+ - to_tuple
+
+## BaseModelOutput
+
+[[autodoc]] modeling_outputs.BaseModelOutput
+
+## BaseModelOutputWithPooling
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPooling
+
+## BaseModelOutputWithCrossAttentions
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithCrossAttentions
+
+## BaseModelOutputWithPoolingAndCrossAttentions
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPoolingAndCrossAttentions
+
+## BaseModelOutputWithPast
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPast
+
+## BaseModelOutputWithPastAndCrossAttentions
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPastAndCrossAttentions
+
+## Seq2SeqModelOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqModelOutput
+
+## CausalLMOutput
+
+[[autodoc]] modeling_outputs.CausalLMOutput
+
+## CausalLMOutputWithCrossAttentions
+
+[[autodoc]] modeling_outputs.CausalLMOutputWithCrossAttentions
+
+## CausalLMOutputWithPast
+
+[[autodoc]] modeling_outputs.CausalLMOutputWithPast
+
+## MaskedLMOutput
+
+[[autodoc]] modeling_outputs.MaskedLMOutput
+
+## Seq2SeqLMOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqLMOutput
+
+## NextSentencePredictorOutput
+
+[[autodoc]] modeling_outputs.NextSentencePredictorOutput
+
+## SequenceClassifierOutput
+
+[[autodoc]] modeling_outputs.SequenceClassifierOutput
+
+## Seq2SeqSequenceClassifierOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqSequenceClassifierOutput
+
+## MultipleChoiceModelOutput
+
+[[autodoc]] modeling_outputs.MultipleChoiceModelOutput
+
+## TokenClassifierOutput
+
+[[autodoc]] modeling_outputs.TokenClassifierOutput
+
+## QuestionAnsweringModelOutput
+
+[[autodoc]] modeling_outputs.QuestionAnsweringModelOutput
+
+## Seq2SeqQuestionAnsweringModelOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqQuestionAnsweringModelOutput
+
+## Seq2SeqSpectrogramOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqSpectrogramOutput
+
+## SemanticSegmenterOutput
+
+[[autodoc]] modeling_outputs.SemanticSegmenterOutput
+
+## ImageClassifierOutput
+
+[[autodoc]] modeling_outputs.ImageClassifierOutput
+
+## ImageClassifierOutputWithNoAttention
+
+[[autodoc]] modeling_outputs.ImageClassifierOutputWithNoAttention
+
+## DepthEstimatorOutput
+
+[[autodoc]] modeling_outputs.DepthEstimatorOutput
+
+## Wav2Vec2BaseModelOutput
+
+[[autodoc]] modeling_outputs.Wav2Vec2BaseModelOutput
+
+## XVectorOutput
+
+[[autodoc]] modeling_outputs.XVectorOutput
+
+## Seq2SeqTSModelOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqTSModelOutput
+
+## Seq2SeqTSPredictionOutput
+
+[[autodoc]] modeling_outputs.Seq2SeqTSPredictionOutput
+
+## SampleTSPredictionOutput
+
+[[autodoc]] modeling_outputs.SampleTSPredictionOutput
+
+## TFBaseModelOutput
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutput
+
+## TFBaseModelOutputWithPooling
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPooling
+
+## TFBaseModelOutputWithPoolingAndCrossAttentions
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPoolingAndCrossAttentions
+
+## TFBaseModelOutputWithPast
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPast
+
+## TFBaseModelOutputWithPastAndCrossAttentions
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPastAndCrossAttentions
+
+## TFSeq2SeqModelOutput
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqModelOutput
+
+## TFCausalLMOutput
+
+[[autodoc]] modeling_tf_outputs.TFCausalLMOutput
+
+## TFCausalLMOutputWithCrossAttentions
+
+[[autodoc]] modeling_tf_outputs.TFCausalLMOutputWithCrossAttentions
+
+## TFCausalLMOutputWithPast
+
+[[autodoc]] modeling_tf_outputs.TFCausalLMOutputWithPast
+
+## TFMaskedLMOutput
+
+[[autodoc]] modeling_tf_outputs.TFMaskedLMOutput
+
+## TFSeq2SeqLMOutput
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqLMOutput
+
+## TFNextSentencePredictorOutput
+
+[[autodoc]] modeling_tf_outputs.TFNextSentencePredictorOutput
+
+## TFSequenceClassifierOutput
+
+[[autodoc]] modeling_tf_outputs.TFSequenceClassifierOutput
+
+## TFSeq2SeqSequenceClassifierOutput
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqSequenceClassifierOutput
+
+## TFMultipleChoiceModelOutput
+
+[[autodoc]] modeling_tf_outputs.TFMultipleChoiceModelOutput
+
+## TFTokenClassifierOutput
+
+[[autodoc]] modeling_tf_outputs.TFTokenClassifierOutput
+
+## TFQuestionAnsweringModelOutput
+
+[[autodoc]] modeling_tf_outputs.TFQuestionAnsweringModelOutput
+
+## TFSeq2SeqQuestionAnsweringModelOutput
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqQuestionAnsweringModelOutput
+
+## FlaxBaseModelOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutput
+
+## FlaxBaseModelOutputWithPast
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutputWithPast
+
+## FlaxBaseModelOutputWithPooling
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutputWithPooling
+
+## FlaxBaseModelOutputWithPastAndCrossAttentions
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutputWithPastAndCrossAttentions
+
+## FlaxSeq2SeqModelOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqModelOutput
+
+## FlaxCausalLMOutputWithCrossAttentions
+
+[[autodoc]] modeling_flax_outputs.FlaxCausalLMOutputWithCrossAttentions
+
+## FlaxMaskedLMOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxMaskedLMOutput
+
+## FlaxSeq2SeqLMOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqLMOutput
+
+## FlaxNextSentencePredictorOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxNextSentencePredictorOutput
+
+## FlaxSequenceClassifierOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxSequenceClassifierOutput
+
+## FlaxSeq2SeqSequenceClassifierOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqSequenceClassifierOutput
+
+## FlaxMultipleChoiceModelOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxMultipleChoiceModelOutput
+
+## FlaxTokenClassifierOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxTokenClassifierOutput
+
+## FlaxQuestionAnsweringModelOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxQuestionAnsweringModelOutput
+
+## FlaxSeq2SeqQuestionAnsweringModelOutput
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqQuestionAnsweringModelOutput
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/pipelines.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/pipelines.md
new file mode 100644
index 0000000000000000000000000000000000000000..3980becebbde36ed8cc224bcb721dd338ac079b0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/pipelines.md
@@ -0,0 +1,498 @@
+
+
+# Pipelines
+
+パイプラインは、推論にモデルを使うための簡単で優れた方法である。パイプラインは、複雑なコードのほとんどを抽象化したオブジェクトです。
+パイプラインは、ライブラリから複雑なコードのほとんどを抽象化したオブジェクトで、名前付き固有表現認識、マスク言語モデリング、感情分析、特徴抽出、質問応答などのタスクに特化したシンプルなAPIを提供します。
+Recognition、Masked Language Modeling、Sentiment Analysis、Feature Extraction、Question Answeringなどのタスクに特化したシンプルなAPIを提供します。以下を参照のこと。
+[タスク概要](../task_summary)を参照してください。
+
+
+パイプラインの抽象化には2つのカテゴリーがある:
+
+- [`pipeline`] は、他のすべてのパイプラインをカプセル化する最も強力なオブジェクトです。
+- タスク固有のパイプラインは、[オーディオ](#audio)、[コンピューター ビジョン](#computer-vision)、[自然言語処理](#natural-language-processing)、および [マルチモーダル](#multimodal) タスクで使用できます。
+
+## The pipeline abstraction
+
+*パイプライン* 抽象化は、他のすべての利用可能なパイプラインのラッパーです。他のものと同様にインスタンス化されます
+パイプラインですが、さらなる生活の質を提供できます。
+
+1 つの項目に対する単純な呼び出し:
+
+```python
+>>> pipe = pipeline("text-classification")
+>>> pipe("This restaurant is awesome")
+[{'label': 'POSITIVE', 'score': 0.9998743534088135}]
+```
+
+[ハブ](https://huggingface.co) の特定のモデルを使用したい場合は、モデルがオンになっている場合はタスクを無視できます。
+ハブはすでにそれを定義しています。
+
+```python
+>>> pipe = pipeline(model="FacebookAI/roberta-large-mnli")
+>>> pipe("This restaurant is awesome")
+[{'label': 'NEUTRAL', 'score': 0.7313136458396912}]
+```
+
+多くの項目に対してパイプラインを呼び出すには、*list* を使用してパイプラインを呼び出すことができます。
+
+```python
+>>> pipe = pipeline("text-classification")
+>>> pipe(["This restaurant is awesome", "This restaurant is awful"])
+[{'label': 'POSITIVE', 'score': 0.9998743534088135},
+ {'label': 'NEGATIVE', 'score': 0.9996669292449951}]
+```
+
+完全なデータセットを反復するには、`Dataset`を直接使用することをお勧めします。これは、割り当てる必要がないことを意味します
+データセット全体を一度に処理することも、自分でバッチ処理を行う必要もありません。これはカスタムループと同じくらい速く動作するはずです。
+GPU。それが問題でない場合は、ためらわずに問題を作成してください。
+
+```python
+import datasets
+from transformers import pipeline
+from transformers.pipelines.pt_utils import KeyDataset
+from tqdm.auto import tqdm
+
+pipe = pipeline("automatic-speech-recognition", model="facebook/wav2vec2-base-960h", device=0)
+dataset = datasets.load_dataset("superb", name="asr", split="test")
+
+# KeyDataset (only *pt*) will simply return the item in the dict returned by the dataset item
+# as we're not interested in the *target* part of the dataset. For sentence pair use KeyPairDataset
+for out in tqdm(pipe(KeyDataset(dataset, "file"))):
+ print(out)
+ # {"text": "NUMBER TEN FRESH NELLY IS WAITING ON YOU GOOD NIGHT HUSBAND"}
+ # {"text": ....}
+ # ....
+```
+
+使いやすくするために、ジェネレーターを使用することもできます。
+
+```python
+from transformers import pipeline
+
+pipe = pipeline("text-classification")
+
+
+def data():
+ while True:
+ # This could come from a dataset, a database, a queue or HTTP request
+ # in a server
+ # Caveat: because this is iterative, you cannot use `num_workers > 1` variable
+ # to use multiple threads to preprocess data. You can still have 1 thread that
+ # does the preprocessing while the main runs the big inference
+ yield "This is a test"
+
+
+for out in pipe(data()):
+ print(out)
+ # {"text": "NUMBER TEN FRESH NELLY IS WAITING ON YOU GOOD NIGHT HUSBAND"}
+ # {"text": ....}
+ # ....
+```
+
+[[autodoc]] pipeline
+
+
+## Pipeline batching
+
+
+すべてのパイプラインでバッチ処理を使用できます。これはうまくいきます
+パイプラインがストリーミング機能を使用するときは常に (つまり、リスト、`dataset`、または `generator`を渡すとき)。
+
+```python
+from transformers import pipeline
+from transformers.pipelines.pt_utils import KeyDataset
+import datasets
+
+dataset = datasets.load_dataset("imdb", name="plain_text", split="unsupervised")
+pipe = pipeline("text-classification", device=0)
+for out in pipe(KeyDataset(dataset, "text"), batch_size=8, truncation="only_first"):
+ print(out)
+ # [{'label': 'POSITIVE', 'score': 0.9998743534088135}]
+ # Exactly the same output as before, but the content are passed
+ # as batches to the model
+```
+
+
+
+
+ただし、これによってパフォーマンスが自動的に向上するわけではありません。状況に応じて、10 倍の高速化または 5 倍の低速化のいずれかになります。
+ハードウェア、データ、使用されている実際のモデルについて。
+
+主に高速化である例:
+
+
+
+
+```python
+from transformers import pipeline
+from torch.utils.data import Dataset
+from tqdm.auto import tqdm
+
+pipe = pipeline("text-classification", device=0)
+
+
+class MyDataset(Dataset):
+ def __len__(self):
+ return 5000
+
+ def __getitem__(self, i):
+ return "This is a test"
+
+
+dataset = MyDataset()
+
+for batch_size in [1, 8, 64, 256]:
+ print("-" * 30)
+ print(f"Streaming batch_size={batch_size}")
+ for out in tqdm(pipe(dataset, batch_size=batch_size), total=len(dataset)):
+ pass
+```
+
+```
+# On GTX 970
+------------------------------
+Streaming no batching
+100%|██████████████████████████████████████████████████████████████████████| 5000/5000 [00:26<00:00, 187.52it/s]
+------------------------------
+Streaming batch_size=8
+100%|█████████████████████████████████████████████████████████████████████| 5000/5000 [00:04<00:00, 1205.95it/s]
+------------------------------
+Streaming batch_size=64
+100%|█████████████████████████████████████████████████████████████████████| 5000/5000 [00:02<00:00, 2478.24it/s]
+------------------------------
+Streaming batch_size=256
+100%|█████████████████████████████████████████████████████████████████████| 5000/5000 [00:01<00:00, 2554.43it/s]
+(diminishing returns, saturated the GPU)
+```
+
+最も速度が低下する例:
+
+
+```python
+class MyDataset(Dataset):
+ def __len__(self):
+ return 5000
+
+ def __getitem__(self, i):
+ if i % 64 == 0:
+ n = 100
+ else:
+ n = 1
+ return "This is a test" * n
+```
+
+これは、他の文に比べて非常に長い文が時折あります。その場合、**全体**のバッチは 400 である必要があります。
+トークンが長いため、バッチ全体が [64, 4] ではなく [64, 400] になり、速度が大幅に低下します。さらに悪いことに、
+バッチが大きくなると、プログラムは単純にクラッシュします。
+
+```
+------------------------------
+Streaming no batching
+100%|█████████████████████████████████████████████████████████████████████| 1000/1000 [00:05<00:00, 183.69it/s]
+------------------------------
+Streaming batch_size=8
+100%|█████████████████████████████████████████████████████████████████████| 1000/1000 [00:03<00:00, 265.74it/s]
+------------------------------
+Streaming batch_size=64
+100%|██████████████████████████████████████████████████████████████████████| 1000/1000 [00:26<00:00, 37.80it/s]
+------------------------------
+Streaming batch_size=256
+ 0%| | 0/1000 [00:00
+ for out in tqdm(pipe(dataset, batch_size=256), total=len(dataset)):
+....
+ q = q / math.sqrt(dim_per_head) # (bs, n_heads, q_length, dim_per_head)
+RuntimeError: CUDA out of memory. Tried to allocate 376.00 MiB (GPU 0; 3.95 GiB total capacity; 1.72 GiB already allocated; 354.88 MiB free; 2.46 GiB reserved in total by PyTorch)
+```
+
+この問題に対する適切な (一般的な) 解決策はなく、使用できる距離はユースケースによって異なる場合があります。のルール
+親指:
+
+ユーザーにとっての経験則は次のとおりです。
+
+- **ハードウェアを使用して、負荷に対するパフォーマンスを測定します。測って、測って、測り続ける。実数というのは、
+ 進むべき唯一の方法。**
+- レイテンシに制約がある場合 (実際の製品が推論を実行している場合)、バッチ処理を行わないでください。
+- CPU を使用している場合は、バッチ処理を行わないでください。
+- GPU でスループットを使用している場合 (大量の静的データでモデルを実行したい場合)、次のようにします。
+
+ - sequence_length (「自然な」データ) のサイズについてまったくわからない場合は、デフォルトではバッチ処理や測定を行わず、
+ 暫定的に追加してみます。失敗した場合に回復するために OOM チェックを追加します (失敗した場合は、ある時点で回復します)。
+ sequence_length を制御します。)
+ - sequence_length が非常に規則的である場合、バッチ処理は非常に興味深いものとなる可能性が高く、測定してプッシュしてください。
+ OOM が発生するまで続けます。
+ - GPU が大きいほど、バッチ処理がより興味深いものになる可能性が高くなります。
+- バッチ処理を有効にしたらすぐに、OOM を適切に処理できることを確認してください。
+
+
+## Pipeline chunk batching
+
+`zero-shot-classification` と `question-answering` は、単一の入力で結果が得られる可能性があるという意味で、少し特殊です。
+モデルの複数の前方パス。通常の状況では、これにより `batch_size` 引数に関する問題が発生します。
+
+この問題を回避するために、これらのパイプラインはどちらも少し特殊になっており、代わりに `ChunkPipeline` になっています。
+通常の `Pipeline`。要するに:
+
+```python
+preprocessed = pipe.preprocess(inputs)
+model_outputs = pipe.forward(preprocessed)
+outputs = pipe.postprocess(model_outputs)
+```
+
+今は次のようになります:
+
+```python
+all_model_outputs = []
+for preprocessed in pipe.preprocess(inputs):
+ model_outputs = pipe.forward(preprocessed)
+ all_model_outputs.append(model_outputs)
+outputs = pipe.postprocess(all_model_outputs)
+```
+
+パイプラインは以下で使用されるため、これはコードに対して非常に透過的である必要があります。
+同じ方法。
+
+パイプラインはバッチを自動的に処理できるため、これは簡略化されたビューです。気にする必要はないという意味です
+入力が実際にトリガーする前方パスの数については、`batch_size` を最適化できます。
+入力とは独立して。前のセクションの注意事項が引き続き適用されます。
+
+## Pipeline custom code
+
+特定のパイプラインをオーバーライドする場合。
+
+目の前のタスクに関する問題を作成することを躊躇しないでください。パイプラインの目標は、使いやすく、ほとんどのユーザーをサポートすることです。
+したがって、`transformers`があなたのユースケースをサポートする可能性があります。
+
+
+単純に試してみたい場合は、次のことができます。
+
+- 選択したパイプラインをサブクラス化します
+
+```python
+class MyPipeline(TextClassificationPipeline):
+ def postprocess():
+ # Your code goes here
+ scores = scores * 100
+ # And here
+
+
+my_pipeline = MyPipeline(model=model, tokenizer=tokenizer, ...)
+# or if you use *pipeline* function, then:
+my_pipeline = pipeline(model="xxxx", pipeline_class=MyPipeline)
+```
+
+これにより、必要なカスタム コードをすべて実行できるようになります。
+
+## Implementing a pipeline
+
+[Implementing a new pipeline](../add_new_pipeline)
+
+## Audio
+
+オーディオ タスクに使用できるパイプラインには次のものがあります。
+
+### AudioClassificationPipeline
+
+[[autodoc]] AudioClassificationPipeline
+ - __call__
+ - all
+
+### AutomaticSpeechRecognitionPipeline
+
+[[autodoc]] AutomaticSpeechRecognitionPipeline
+ - __call__
+ - all
+
+### TextToAudioPipeline
+
+[[autodoc]] TextToAudioPipeline
+ - __call__
+ - all
+
+
+### ZeroShotAudioClassificationPipeline
+
+[[autodoc]] ZeroShotAudioClassificationPipeline
+ - __call__
+ - all
+
+## Computer vision
+
+コンピューター ビジョン タスクに使用できるパイプラインには次のものがあります。
+
+### DepthEstimationPipeline
+[[autodoc]] DepthEstimationPipeline
+ - __call__
+ - all
+
+### ImageClassificationPipeline
+
+[[autodoc]] ImageClassificationPipeline
+ - __call__
+ - all
+
+### ImageSegmentationPipeline
+
+[[autodoc]] ImageSegmentationPipeline
+ - __call__
+ - all
+
+### ImageToImagePipeline
+
+[[autodoc]] ImageToImagePipeline
+ - __call__
+ - all
+
+### ObjectDetectionPipeline
+
+[[autodoc]] ObjectDetectionPipeline
+ - __call__
+ - all
+
+### VideoClassificationPipeline
+
+[[autodoc]] VideoClassificationPipeline
+ - __call__
+ - all
+
+### ZeroShotImageClassificationPipeline
+
+[[autodoc]] ZeroShotImageClassificationPipeline
+ - __call__
+ - all
+
+### ZeroShotObjectDetectionPipeline
+
+[[autodoc]] ZeroShotObjectDetectionPipeline
+ - __call__
+ - all
+
+## Natural Language Processing
+
+自然言語処理タスクに使用できるパイプラインには次のものがあります。
+
+### FillMaskPipeline
+
+[[autodoc]] FillMaskPipeline
+ - __call__
+ - all
+
+### NerPipeline
+
+[[autodoc]] NerPipeline
+
+詳細については、[`TokenClassificationPipeline`] を参照してください。
+
+### QuestionAnsweringPipeline
+
+[[autodoc]] QuestionAnsweringPipeline
+ - __call__
+ - all
+
+### SummarizationPipeline
+
+[[autodoc]] SummarizationPipeline
+ - __call__
+ - all
+
+### TableQuestionAnsweringPipeline
+
+[[autodoc]] TableQuestionAnsweringPipeline
+ - __call__
+
+### TextClassificationPipeline
+
+[[autodoc]] TextClassificationPipeline
+ - __call__
+ - all
+
+### TextGenerationPipeline
+
+[[autodoc]] TextGenerationPipeline
+ - __call__
+ - all
+
+### Text2TextGenerationPipeline
+
+[[autodoc]] Text2TextGenerationPipeline
+ - __call__
+ - all
+
+### TokenClassificationPipeline
+
+[[autodoc]] TokenClassificationPipeline
+ - __call__
+ - all
+
+### TranslationPipeline
+
+[[autodoc]] TranslationPipeline
+ - __call__
+ - all
+
+### ZeroShotClassificationPipeline
+
+[[autodoc]] ZeroShotClassificationPipeline
+ - __call__
+ - all
+
+## Multimodal
+
+マルチモーダル タスクに使用できるパイプラインには次のものがあります。
+
+### DocumentQuestionAnsweringPipeline
+
+[[autodoc]] DocumentQuestionAnsweringPipeline
+ - __call__
+ - all
+
+### FeatureExtractionPipeline
+
+[[autodoc]] FeatureExtractionPipeline
+ - __call__
+ - all
+
+### ImageFeatureExtractionPipeline
+
+[[autodoc]] ImageFeatureExtractionPipeline
+ - __call__
+ - all
+
+### ImageToTextPipeline
+
+[[autodoc]] ImageToTextPipeline
+ - __call__
+ - all
+
+### ImageTextToTextPipeline
+
+[[autodoc]] ImageTextToTextPipeline
+ - __call__
+ - all
+
+### VisualQuestionAnsweringPipeline
+
+[[autodoc]] VisualQuestionAnsweringPipeline
+ - __call__
+ - all
+
+## Parent class: `Pipeline`
+
+[[autodoc]] Pipeline
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/processors.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/processors.md
new file mode 100644
index 0000000000000000000000000000000000000000..63b94af6ea43f3df9b932f56d20995bd734edb0f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/processors.md
@@ -0,0 +1,160 @@
+
+
+# Processors
+
+Transformers ライブラリでは、プロセッサは 2 つの異なる意味を持ちます。
+- [Wav2Vec2](../model_doc/wav2vec2) などのマルチモーダル モデルの入力を前処理するオブジェクト (音声とテキスト)
+ または [CLIP](../model_doc/clip) (テキストとビジョン)
+- 古いバージョンのライブラリで GLUE または SQUAD のデータを前処理するために使用されていたオブジェクトは非推奨になりました。
+
+## Multi-modal processors
+
+マルチモーダル モデルでは、オブジェクトが複数のモダリティ (テキスト、
+視覚と音声)。これは、2 つ以上の処理オブジェクトをグループ化するプロセッサーと呼ばれるオブジェクトによって処理されます。
+トークナイザー (テキスト モダリティ用)、画像プロセッサー (視覚用)、特徴抽出器 (オーディオ用) など。
+
+これらのプロセッサは、保存およびロード機能を実装する次の基本クラスを継承します。
+
+[[autodoc]] ProcessorMixin
+
+## Deprecated processors
+
+すべてのプロセッサは、同じアーキテクチャに従っています。
+[`~data.processors.utils.DataProcessor`]。プロセッサは次のリストを返します。
+[`~data.processors.utils.InputExample`]。これら
+[`~data.processors.utils.InputExample`] は次のように変換できます。
+[`~data.processors.utils.Input features`] をモデルにフィードします。
+
+[[autodoc]] data.processors.utils.DataProcessor
+
+[[autodoc]] data.processors.utils.InputExample
+
+[[autodoc]] data.processors.utils.InputFeatures
+
+## GLUE
+
+[一般言語理解評価 (GLUE)](https://gluebenchmark.com/) は、
+既存の NLU タスクの多様なセットにわたるモデルのパフォーマンス。紙と同時発売された [GLUE: A
+自然言語理解のためのマルチタスクベンチマークおよび分析プラットフォーム](https://openreview.net/pdf?id=rJ4km2R5t7)
+
+このライブラリは、MRPC、MNLI、MNLI (不一致)、CoLA、SST2、STSB、
+QQP、QNLI、RTE、WNLI。
+
+それらのプロセッサは次のとおりです。
+
+- [`~data.processors.utils.MrpcProcessor`]
+- [`~data.processors.utils.MnliProcessor`]
+- [`~data.processors.utils.MnliMismatchedProcessor`]
+- [`~data.processors.utils.Sst2Processor`]
+- [`~data.processors.utils.StsbProcessor`]
+- [`~data.processors.utils.QqpProcessor`]
+- [`~data.processors.utils.QnliProcessor`]
+- [`~data.processors.utils.RteProcessor`]
+- [`~data.processors.utils.WnliProcessor`]
+
+
+さらに、次のメソッドを使用して、データ ファイルから値をロードし、それらをリストに変換することができます。
+[`~data.processors.utils.InputExample`]。
+
+[[autodoc]] data.processors.glue.glue_convert_examples_to_features
+
+## XNLI
+
+[クロスリンガル NLI コーパス (XNLI)](https://www.nyu.edu/projects/bowman/xnli/) は、
+言語を超えたテキスト表現の品質。 XNLI は、[*MultiNLI*](http://www.nyu.edu/projects/bowman/multinli/) に基づくクラウドソースのデータセットです。テキストのペアには、15 個のテキスト含意アノテーションがラベル付けされています。
+さまざまな言語 (英語などの高リソース言語とスワヒリ語などの低リソース言語の両方を含む)。
+
+論文 [XNLI: Evaluating Cross-lingual Sentence Representations](https://arxiv.org/abs/1809.05053) と同時にリリースされました。
+
+このライブラリは、XNLI データをロードするプロセッサをホストします。
+
+- [`~data.processors.utils.XnliProcessor`]
+
+テストセットにはゴールドラベルが付いているため、評価はテストセットで行われますのでご了承ください。
+
+これらのプロセッサを使用する例は、[run_xnli.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-classification/run_xnli.py) スクリプトに示されています。
+
+## SQuAD
+
+[The Stanford Question Answering Dataset (SQuAD)](https://rajpurkar.github.io/SQuAD-explorer//) は、次のベンチマークです。
+質問応答に関するモデルのパフォーマンスを評価します。 v1.1 と v2.0 の 2 つのバージョンが利用可能です。最初のバージョン
+(v1.1) は、論文 [SQuAD: 100,000+ question for Machine Comprehension of Text](https://arxiv.org/abs/1606.05250) とともにリリースされました。 2 番目のバージョン (v2.0) は、論文 [Know What You Don't と同時にリリースされました。
+知っておくべき: SQuAD の答えられない質問](https://arxiv.org/abs/1806.03822)。
+
+このライブラリは、次の 2 つのバージョンのそれぞれのプロセッサをホストします。
+
+### Processors
+
+それらのプロセッサは次のとおりです。
+
+- [`~data.processors.utils.SquadV1Processor`]
+- [`~data.processors.utils.SquadV2Processor`]
+
+どちらも抽象クラス [`~data.processors.utils.SquadProcessor`] を継承しています。
+
+[[autodoc]] data.processors.squad.SquadProcessor
+ - all
+
+さらに、次のメソッドを使用して、SQuAD の例を次の形式に変換できます。
+モデルの入力として使用できる [`~data.processors.utils.SquadFeatures`]。
+
+[[autodoc]] data.processors.squad.squad_convert_examples_to_features
+
+これらのプロセッサと前述の方法は、データを含むファイルだけでなく、
+*tensorflow_datasets* パッケージ。以下に例を示します。
+
+### Example usage
+
+以下にプロセッサを使用した例と、データ ファイルを使用した変換方法を示します。
+
+```python
+# Loading a V2 processor
+processor = SquadV2Processor()
+examples = processor.get_dev_examples(squad_v2_data_dir)
+
+# Loading a V1 processor
+processor = SquadV1Processor()
+examples = processor.get_dev_examples(squad_v1_data_dir)
+
+features = squad_convert_examples_to_features(
+ examples=examples,
+ tokenizer=tokenizer,
+ max_seq_length=max_seq_length,
+ doc_stride=args.doc_stride,
+ max_query_length=max_query_length,
+ is_training=not evaluate,
+)
+```
+
+*tensorflow_datasets* の使用は、データ ファイルを使用するのと同じくらい簡単です。
+
+```python
+# tensorflow_datasets only handle Squad V1.
+tfds_examples = tfds.load("squad")
+examples = SquadV1Processor().get_examples_from_dataset(tfds_examples, evaluate=evaluate)
+
+features = squad_convert_examples_to_features(
+ examples=examples,
+ tokenizer=tokenizer,
+ max_seq_length=max_seq_length,
+ doc_stride=args.doc_stride,
+ max_query_length=max_query_length,
+ is_training=not evaluate,
+)
+```
+
+これらのプロセッサを使用する別の例は、[run_squad.py](https://github.com/huggingface/transformers/tree/main/examples/legacy/question-answering/run_squad.py) スクリプトに示されています。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/quantization.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/quantization.md
new file mode 100644
index 0000000000000000000000000000000000000000..a93d06b257459e0fa441e9149084997331ca2241
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/quantization.md
@@ -0,0 +1,447 @@
+
+
+# Quantize 🤗 Transformers models
+
+## `AutoGPTQ` Integration
+
+
+🤗 Transformers には、言語モデルで GPTQ 量子化を実行するための `optimum` API が統合されています。パフォーマンスを大幅に低下させることなく、推論速度を高速化することなく、モデルを 8、4、3、さらには 2 ビットでロードおよび量子化できます。これは、ほとんどの GPU ハードウェアでサポートされています。
+
+量子化モデルの詳細については、以下を確認してください。
+- [GPTQ](https://arxiv.org/pdf/2210.17323.pdf) 論文
+- GPTQ 量子化に関する `optimum` [ガイド](https://huggingface.co/docs/optimum/llm_quantization/usage_guides/quantization)
+- バックエンドとして使用される [`AutoGPTQ`](https://github.com/PanQiWei/AutoGPTQ) ライブラリ
+
+### Requirements
+
+以下のコードを実行するには、以下の要件がインストールされている必要があります:
+
+- 最新の `AutoGPTQ` ライブラリをインストールする。
+`pip install auto-gptq` をインストールする。
+
+- 最新の `optimum` をソースからインストールする。
+`git+https://github.com/huggingface/optimum.git` をインストールする。
+
+- 最新の `transformers` をソースからインストールする。
+最新の `transformers` をソースからインストールする `pip install git+https://github.com/huggingface/transformers.git`
+
+- 最新の `accelerate` ライブラリをインストールする。
+`pip install --upgrade accelerate` を実行する。
+
+GPTQ統合は今のところテキストモデルのみをサポートしているので、視覚、音声、マルチモーダルモデルでは予期せぬ挙動に遭遇するかもしれないことに注意してください。
+
+### Load and quantize a model
+
+GPTQ は、量子化モデルを使用する前に重みのキャリブレーションを必要とする量子化方法です。トランスフォーマー モデルを最初から量子化する場合は、量子化モデルを作成するまでに時間がかかることがあります (`facebook/opt-350m`モデルの Google colab では約 5 分)。
+
+したがって、GPTQ 量子化モデルを使用するシナリオは 2 つあります。最初の使用例は、ハブで利用可能な他のユーザーによってすでに量子化されたモデルをロードすることです。2 番目の使用例は、モデルを最初から量子化し、保存するかハブにプッシュして、他のユーザーが使用できるようにすることです。それも使ってください。
+
+#### GPTQ Configuration
+
+モデルをロードして量子化するには、[`GPTQConfig`] を作成する必要があります。データセットを準備するには、`bits`の数、量子化を調整するための`dataset`、およびモデルの`Tokenizer`を渡す必要があります。
+
+```python
+model_id = "facebook/opt-125m"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+gptq_config = GPTQConfig(bits=4, dataset = "c4", tokenizer=tokenizer)
+```
+
+独自のデータセットを文字列のリストとして渡すことができることに注意してください。ただし、GPTQ 論文のデータセットを使用することを強くお勧めします。
+
+```python
+dataset = ["auto-gptq is an easy-to-use model quantization library with user-friendly apis, based on GPTQ algorithm."]
+quantization = GPTQConfig(bits=4, dataset = dataset, tokenizer=tokenizer)
+```
+
+#### Quantization
+
+`from_pretrained` を使用し、`quantization_config` を設定することでモデルを量子化できます。
+
+```python
+from transformers import AutoModelForCausalLM
+model = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=gptq_config)
+```
+
+モデルを量子化するには GPU が必要であることに注意してください。モデルを CPU に配置し、量子化するためにモジュールを GPU に前後に移動させます。
+
+CPU オフロードの使用中に GPU の使用量を最大化したい場合は、`device_map = "auto"` を設定できます。
+
+```python
+from transformers import AutoModelForCausalLM
+model = AutoModelForCausalLM.from_pretrained(model_id, device_map="auto", quantization_config=gptq_config)
+```
+
+ディスク オフロードはサポートされていないことに注意してください。さらに、データセットが原因でメモリが不足している場合は、`from_pretained` で `max_memory` を渡す必要がある場合があります。 `device_map`と`max_memory`の詳細については、この [ガイド](https://huggingface.co/docs/accelerate/usage_guides/big_modeling#designing-a-device-map) を参照してください。
+
+
+GPTQ 量子化は、現時点ではテキスト モデルでのみ機能します。さらに、量子化プロセスはハードウェアによっては長時間かかる場合があります (NVIDIA A100 を使用した場合、175B モデル = 4 gpu 時間)。モデルの GPTQ 量子化バージョンが存在しない場合は、ハブで確認してください。そうでない場合は、github で要求を送信できます。
+
+
+### Push quantized model to 🤗 Hub
+
+他の 🤗 モデルと同様に、`push_to_hub` を使用して量子化モデルをハブにプッシュできます。量子化構成は保存され、モデルに沿ってプッシュされます。
+
+```python
+quantized_model.push_to_hub("opt-125m-gptq")
+tokenizer.push_to_hub("opt-125m-gptq")
+```
+
+量子化されたモデルをローカル マシンに保存したい場合は、`save_pretrained` を使用して行うこともできます。
+
+
+```python
+quantized_model.save_pretrained("opt-125m-gptq")
+tokenizer.save_pretrained("opt-125m-gptq")
+```
+
+`device_map` を使用してモデルを量子化した場合は、保存する前にモデル全体を GPU または `cpu` のいずれかに移動してください。
+
+```python
+quantized_model.to("cpu")
+quantized_model.save_pretrained("opt-125m-gptq")
+```
+
+### Load a quantized model from the 🤗 Hub
+
+`from_pretrained`を使用して、量子化されたモデルをハブからロードできます。
+属性 `quantization_config` がモデル設定オブジェクトに存在することを確認して、プッシュされた重みが量子化されていることを確認します。
+
+```python
+from transformers import AutoModelForCausalLM
+model = AutoModelForCausalLM.from_pretrained("{your_username}/opt-125m-gptq")
+```
+
+必要以上のメモリを割り当てずにモデルをより速くロードしたい場合は、`device_map` 引数は量子化モデルでも機能します。 `accelerate`ライブラリがインストールされていることを確認してください。
+
+```python
+from transformers import AutoModelForCausalLM
+model = AutoModelForCausalLM.from_pretrained("{your_username}/opt-125m-gptq", device_map="auto")
+```
+
+### Exllama kernels for faster inference
+
+4 ビット モデルの場合、推論速度を高めるために exllama カーネルを使用できます。デフォルトで有効になっています。 [`GPTQConfig`] で `disable_exllama` を渡すことで、その動作を変更できます。これにより、設定に保存されている量子化設定が上書きされます。カーネルに関連する属性のみを上書きできることに注意してください。さらに、exllama カーネルを使用したい場合は、モデル全体を GPU 上に置く必要があります。
+
+
+```py
+import torch
+gptq_config = GPTQConfig(bits=4, disable_exllama=False)
+model = AutoModelForCausalLM.from_pretrained("{your_username}/opt-125m-gptq", device_map="auto", quantization_config = gptq_config)
+```
+
+現時点では 4 ビット モデルのみがサポートされていることに注意してください。さらに、peft を使用して量子化モデルを微調整している場合は、exllama カーネルを非アクティブ化することをお勧めします。
+
+#### Fine-tune a quantized model
+
+Hugging Face エコシステムのアダプターの公式サポートにより、GPTQ で量子化されたモデルを微調整できます。
+詳細については、[`peft`](https://github.com/huggingface/peft) ライブラリをご覧ください。
+
+### Example demo
+
+GPTQ を使用してモデルを量子化する方法と、peft を使用して量子化されたモデルを微調整する方法については、Google Colab [ノートブック](https://colab.research.google.com/drive/1_TIrmuKOFhuRRiTWN94iLKUFu6ZX4ceb?usp=sharing) を参照してください。
+
+### GPTQConfig
+
+[[autodoc]] GPTQConfig
+
+## `bitsandbytes` Integration
+
+🤗 Transformers は、`bitsandbytes` で最もよく使用されるモジュールと緊密に統合されています。数行のコードでモデルを 8 ビット精度でロードできます。
+これは、`bitsandbytes`の `0.37.0`リリース以降、ほとんどの GPU ハードウェアでサポートされています。
+
+量子化方法の詳細については、[LLM.int8()](https://arxiv.org/abs/2208.07339) 論文、または [ブログ投稿](https://huggingface.co/blog/hf-bitsandbytes-) をご覧ください。統合)コラボレーションについて。
+
+`0.39.0`リリース以降、FP4 データ型を活用し、4 ビット量子化を使用して`device_map`をサポートする任意のモデルをロードできます。
+
+独自の pytorch モデルを量子化したい場合は、🤗 Accelerate ライブラリの [ドキュメント](https://huggingface.co/docs/accelerate/main/en/usage_guides/quantization) をチェックしてください。
+
+`bitsandbytes`統合を使用してできることは次のとおりです
+
+### General usage
+
+モデルが 🤗 Accelerate による読み込みをサポートし、`torch.nn.Linear` レイヤーが含まれている限り、 [`~PreTrainedModel.from_pretrained`] メソッドを呼び出すときに `load_in_8bit` または `load_in_4bit` 引数を使用してモデルを量子化できます。これはどのようなモダリティでも同様に機能するはずです。
+
+```python
+from transformers import AutoModelForCausalLM
+
+model_8bit = AutoModelForCausalLM.from_pretrained("facebook/opt-350m", load_in_8bit=True)
+model_4bit = AutoModelForCausalLM.from_pretrained("facebook/opt-350m", load_in_4bit=True)
+```
+
+デフォルトでは、他のすべてのモジュール (例: `torch.nn.LayerNorm`) は `torch.float16` に変換されますが、その `dtype` を変更したい場合は、`torch_dtype` 引数を上書きできます。
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM
+
+>>> model_8bit = AutoModelForCausalLM.from_pretrained("facebook/opt-350m", load_in_8bit=True, torch_dtype=torch.float32)
+>>> model_8bit.model.decoder.layers[-1].final_layer_norm.weight.dtype
+torch.float32
+```
+
+### FP4 quantization
+
+#### Requirements
+
+以下のコード スニペットを実行する前に、以下の要件がインストールされていることを確認してください。
+
+- 最新の`bitsandbytes`ライブラリ
+`pip install bitsandbytes>=0.39.0`
+
+- 最新の`accelerate`をインストールする
+`pip install --upgrade accelerate`
+
+- 最新の `transformers` をインストールする
+`pip install --upgrade transformers`
+
+#### Tips and best practices
+
+- **高度な使用法:** 可能なすべてのオプションを使用した 4 ビット量子化の高度な使用法については、[この Google Colab ノートブック](https://colab.research.google.com/drive/1ge2F1QSK8Q7h0hn3YKuBCOAS0bK8E0wf) を参照してください。
+
+- **`batch_size=1` による高速推論 :** bitsandbytes の `0.40.0` リリース以降、`batch_size=1` では高速推論の恩恵を受けることができます。 [これらのリリース ノート](https://github.com/TimDettmers/bitsandbytes/releases/tag/0.40.0) を確認し、この機能を活用するには`0.40.0`以降のバージョンを使用していることを確認してください。箱の。
+
+- **トレーニング:** [QLoRA 論文](https://arxiv.org/abs/2305.14314) によると、4 ビット基本モデルをトレーニングする場合 (例: LoRA アダプターを使用)、`bnb_4bit_quant_type='nf4'` を使用する必要があります。 。
+
+- **推論:** 推論の場合、`bnb_4bit_quant_type` はパフォーマンスに大きな影響を与えません。ただし、モデルの重みとの一貫性を保つために、必ず同じ `bnb_4bit_compute_dtype` および `torch_dtype` 引数を使用してください。
+
+
+#### Load a large model in 4bit
+
+`.from_pretrained` メソッドを呼び出すときに `load_in_4bit=True` を使用すると、メモリ使用量を (おおよそ) 4 で割ることができます。
+
+```python
+# pip install transformers accelerate bitsandbytes
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "bigscience/bloom-1b7"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id, device_map="auto", load_in_4bit=True)
+```
+
+
+
+モデルが 4 ビットでロードされると、現時点では量子化された重みをハブにプッシュすることはできないことに注意してください。 4 ビットの重みはまだサポートされていないため、トレーニングできないことにも注意してください。ただし、4 ビット モデルを使用して追加のパラメーターをトレーニングすることもできます。これについては次のセクションで説明します。
+
+
+
+### Load a large model in 8bit
+
+`.from_pretrained` メソッドを呼び出すときに `load_in_8bit=True` 引数を使用すると、メモリ要件をおよそ半分にしてモデルをロードできます。
+
+```python
+# pip install transformers accelerate bitsandbytes
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model_id = "bigscience/bloom-1b7"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+
+次に、通常 [`PreTrainedModel`] を使用するのと同じようにモデルを使用します。
+
+`get_memory_footprint` メソッドを使用して、モデルのメモリ フットプリントを確認できます。
+
+```python
+print(model.get_memory_footprint())
+```
+
+この統合により、大きなモデルを小さなデバイスにロードし、問題なく実行できるようになりました。
+
+
+モデルが 8 ビットでロードされると、最新の `transformers`と`bitsandbytes`を使用する場合を除き、量子化された重みをハブにプッシュすることは現在不可能であることに注意してください。 8 ビットの重みはまだサポートされていないため、トレーニングできないことにも注意してください。ただし、8 ビット モデルを使用して追加のパラメーターをトレーニングすることもできます。これについては次のセクションで説明します。
+また、`device_map` はオプションですが、利用可能なリソース上でモデルを効率的にディスパッチするため、推論には `device_map = 'auto'` を設定することが推奨されます。
+
+
+
+#### Advanced use cases
+
+ここでは、FP4 量子化を使用して実行できるいくつかの高度な使用例について説明します。
+
+##### Change the compute dtype
+
+compute dtype は、計算中に使用される dtype を変更するために使用されます。たとえば、隠し状態は`float32`にありますが、高速化のために計算を bf16 に設定できます。デフォルトでは、compute dtype は `float32` に設定されます。
+
+```python
+import torch
+from transformers import BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16)
+```
+
+##### Using NF4 (Normal Float 4) data type
+
+NF4 データ型を使用することもできます。これは、正規分布を使用して初期化された重みに適合した新しい 4 ビット データ型です。その実行のために:
+
+```python
+from transformers import BitsAndBytesConfig
+
+nf4_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+)
+
+model_nf4 = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=nf4_config)
+```
+
+##### Use nested quantization for more memory efficient inference
+
+また、ネストされた量子化手法を使用することをお勧めします。これにより、パフォーマンスを追加することなく、より多くのメモリが節約されます。経験的な観察から、これにより、NVIDIA-T4 16GB 上でシーケンス長 1024、バッチ サイズ 1、勾配累積ステップ 4 の llama-13b モデルを微調整することが可能になります。
+
+```python
+from transformers import BitsAndBytesConfig
+
+double_quant_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_use_double_quant=True,
+)
+
+model_double_quant = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=double_quant_config)
+```
+
+
+### Push quantized models on the 🤗 Hub
+
+`push_to_hub`メソッドを単純に使用することで、量子化されたモデルをハブにプッシュできます。これにより、最初に量子化構成ファイルがプッシュされ、次に量子化されたモデルの重みがプッシュされます。
+この機能を使用できるようにするには、必ず `bitsandbytes>0.37.2` を使用してください (この記事の執筆時点では、`bitsandbytes==0.38.0.post1` でテストしました)。
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model = AutoModelForCausalLM.from_pretrained("bigscience/bloom-560m", quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+tokenizer = AutoTokenizer.from_pretrained("bigscience/bloom-560m")
+
+model.push_to_hub("bloom-560m-8bit")
+```
+
+
+
+大規模なモデルでは、ハブ上で 8 ビット モデルをプッシュすることが強く推奨されます。これにより、コミュニティはメモリ フットプリントの削減と、たとえば Google Colab での大規模なモデルの読み込みによる恩恵を受けることができます。
+
+
+
+### Load a quantized model from the 🤗 Hub
+
+`from_pretrained`メソッドを使用して、ハブから量子化モデルをロードできます。属性 `quantization_config` がモデル設定オブジェクトに存在することを確認して、プッシュされた重みが量子化されていることを確認します。
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("{your_username}/bloom-560m-8bit", device_map="auto")
+```
+
+この場合、引数 `load_in_8bit=True` を指定する必要はありませんが、`bitsandbytes` と `accelerate` がインストールされていることを確認する必要があることに注意してください。
+また、`device_map` はオプションですが、利用可能なリソース上でモデルを効率的にディスパッチするため、推論には `device_map = 'auto'` を設定することが推奨されます。
+
+### Advanced use cases
+
+このセクションは、8 ビット モデルのロードと実行以外に何ができるかを探求したい上級ユーザーを対象としています。
+
+#### Offload between `cpu` and `gpu`
+
+この高度な使用例の 1 つは、モデルをロードし、`CPU`と`GPU`の間で重みをディスパッチできることです。 CPU 上でディスパッチされる重みは **8 ビットに変換されない**ため、`float32`に保持されることに注意してください。この機能は、非常に大規模なモデルを適合させ、そのモデルを GPU と CPU の間でディスパッチしたいユーザーを対象としています。
+
+まず、`transformers` から [`BitsAndBytesConfig`] をロードし、属性 `llm_int8_enable_fp32_cpu_offload` を `True` に設定します。
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(llm_int8_enable_fp32_cpu_offload=True)
+```
+
+`bigscience/bloom-1b7`モデルをロードする必要があり、`lm_head`を除くモデル全体に適合するのに十分な GPU RAM があるとします。したがって、次のようにカスタム device_map を作成します。
+
+```python
+device_map = {
+ "transformer.word_embeddings": 0,
+ "transformer.word_embeddings_layernorm": 0,
+ "lm_head": "cpu",
+ "transformer.h": 0,
+ "transformer.ln_f": 0,
+}
+```
+
+そして、次のようにモデルをロードします。
+```python
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ "bigscience/bloom-1b7",
+ device_map=device_map,
+ quantization_config=quantization_config,
+)
+```
+
+以上です!モデルを楽しんでください!
+
+#### Play with `llm_int8_threshold`
+
+`llm_int8_threshold` 引数を操作して、外れ値のしきい値を変更できます。 外れ値 とは、特定のしきい値より大きい隠れた状態の値です。
+これは、`LLM.int8()`論文で説明されている外れ値検出の外れ値しきい値に対応します。このしきい値を超える隠し状態の値は外れ値とみなされ、それらの値に対する操作は fp16 で実行されます。通常、値は正規分布します。つまり、ほとんどの値は [-3.5, 3.5] の範囲内にありますが、大規模なモデルでは大きく異なる分布を示す例外的な系統的外れ値がいくつかあります。これらの外れ値は、多くの場合 [-60, -6] または [6, 60] の範囲内にあります。 Int8 量子化は、大きさが 5 程度までの値ではうまく機能しますが、それを超えると、パフォーマンスが大幅に低下します。適切なデフォルトのしきい値は 6 ですが、より不安定なモデル (小規模なモデル、微調整) では、より低いしきい値が必要になる場合があります。
+この引数は、モデルの推論速度に影響を与える可能性があります。このパラメータを試してみて、ユースケースに最適なパラメータを見つけることをお勧めします。
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model_id = "bigscience/bloom-1b7"
+
+quantization_config = BitsAndBytesConfig(
+ llm_int8_threshold=10,
+)
+
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ model_id,
+ device_map=device_map,
+ quantization_config=quantization_config,
+)
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+```
+
+#### Skip the conversion of some modules
+
+一部のモデルには、安定性を確保するために 8 ビットに変換する必要がないモジュールがいくつかあります。たとえば、ジュークボックス モデルには、スキップする必要があるいくつかの `lm_head` モジュールがあります。 `llm_int8_skip_modules` で遊んでみる
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model_id = "bigscience/bloom-1b7"
+
+quantization_config = BitsAndBytesConfig(
+ llm_int8_skip_modules=["lm_head"],
+)
+
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ model_id,
+ device_map=device_map,
+ quantization_config=quantization_config,
+)
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+```
+
+#### Fine-tune a model that has been loaded in 8-bit
+
+Hugging Face エコシステムのアダプターの公式サポートにより、8 ビットでロードされたモデルを微調整できます。
+これにより、単一の Google Colab で`flan-t5-large`や`facebook/opt-6.7b`などの大規模モデルを微調整することができます。詳細については、[`peft`](https://github.com/huggingface/peft) ライブラリをご覧ください。
+
+トレーニング用のモデルをロードするときに `device_map` を渡す必要がないことに注意してください。モデルが GPU に自動的にロードされます。必要に応じて、デバイス マップを特定のデバイスに設定することもできます (例: `cuda:0`、`0`、`torch.device('cuda:0')`)。 `device_map=auto`は推論のみに使用する必要があることに注意してください。
+
+### BitsAndBytesConfig
+
+[[autodoc]] BitsAndBytesConfig
+
+## Quantization with 🤗 `optimum`
+
+`optimum`でサポートされている量子化方法の詳細については、[Optimum ドキュメント](https://huggingface.co/docs/optimum/index) を参照し、これらが自分のユースケースに適用できるかどうかを確認してください。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/text_generation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/text_generation.md
new file mode 100644
index 0000000000000000000000000000000000000000..18477d97e626d1df942604f4c806cc17268744b2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/text_generation.md
@@ -0,0 +1,56 @@
+
+
+# Generation
+
+各フレームワークには、それぞれの `GenerationMixin` クラスに実装されたテキスト生成のための Generate メソッドがあります。
+
+- PyTorch [`~generation.GenerationMixin.generate`] は [`~generation.GenerationMixin`] に実装されています。
+- TensorFlow [`~generation.TFGenerationMixin.generate`] は [`~generation.TFGenerationMixin`] に実装されています。
+- Flax/JAX [`~generation.FlaxGenerationMixin.generate`] は [`~generation.FlaxGenerationMixin`] に実装されています。
+
+選択したフレームワークに関係なく、[`~generation.GenerationConfig`] を使用して生成メソッドをパラメータ化できます。
+クラスインスタンス。動作を制御する生成パラメータの完全なリストについては、このクラスを参照してください。
+生成方法のこと。
+
+モデルの生成構成を検査する方法、デフォルトとは何か、パラメーターをアドホックに変更する方法を学習するには、
+カスタマイズされた生成構成を作成して保存する方法については、「
+[テキスト生成戦略ガイド](../generation_strategies)。このガイドでは、関連機能の使用方法についても説明しています。
+トークンストリーミングのような。
+
+## GenerationConfig
+
+[[autodoc]] generation.GenerationConfig
+ - from_pretrained
+ - from_model_config
+ - save_pretrained
+
+## GenerationMixin
+
+[[autodoc]] generation.GenerationMixin
+ - generate
+ - compute_transition_scores
+
+## TFGenerationMixin
+
+[[autodoc]] generation.TFGenerationMixin
+ - generate
+ - compute_transition_scores
+
+## FlaxGenerationMixin
+
+[[autodoc]] generation.FlaxGenerationMixin
+ - generate
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/tokenizer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/tokenizer.md
new file mode 100644
index 0000000000000000000000000000000000000000..1cf5885bc81286d4f09dad8cca4ef1ff2e76347a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/tokenizer.md
@@ -0,0 +1,80 @@
+
+
+# Tokenizer
+
+トークナイザーは、モデルの入力の準備を担当します。ライブラリには、すべてのモデルのトークナイザーが含まれています。ほとんど
+トークナイザーの一部は、完全な Python 実装と、
+Rust ライブラリ [🤗 Tokenizers](https://github.com/huggingface/tokenizers)。 「高速」実装では次のことが可能になります。
+
+1. 特にバッチトークン化を行う場合の大幅なスピードアップと
+2. 元の文字列 (文字と単語) とトークン空間の間でマッピングする追加のメソッド (例:
+ 特定の文字を含むトークンのインデックス、または特定のトークンに対応する文字の範囲)。
+
+基本クラス [`PreTrainedTokenizer`] および [`PreTrainedTokenizerFast`]
+モデル入力の文字列入力をエンコードし (以下を参照)、Python をインスタンス化/保存するための一般的なメソッドを実装します。
+ローカル ファイルまたはディレクトリ、またはライブラリによって提供される事前トレーニング済みトークナイザーからの「高速」トークナイザー
+(HuggingFace の AWS S3 リポジトリからダウンロード)。二人とも頼りにしているのは、
+共通メソッドを含む [`~tokenization_utils_base.PreTrainedTokenizerBase`]
+[`~tokenization_utils_base.SpecialTokensMixin`]。
+
+したがって、[`PreTrainedTokenizer`] と [`PreTrainedTokenizerFast`] はメインを実装します。
+すべてのトークナイザーを使用するためのメソッド:
+
+- トークン化 (文字列をサブワード トークン文字列に分割)、トークン文字列を ID に変換したり、その逆の変換を行ったりします。
+ エンコード/デコード (つまり、トークン化と整数への変換)。
+- 基礎となる構造 (BPE、SentencePiece...) から独立した方法で、語彙に新しいトークンを追加します。
+- 特別なトークン (マスク、文の始まりなど) の管理: トークンの追加、属性への割り当て。
+ トークナイザーにより、簡単にアクセスでき、トークン化中に分割されないようにすることができます。
+
+[`BatchEncoding`] は、
+[`~tokenization_utils_base.PreTrainedTokenizerBase`] のエンコード メソッド (`__call__`、
+`encode_plus` および `batch_encode_plus`) であり、Python 辞書から派生しています。トークナイザーが純粋な Python の場合
+tokenizer の場合、このクラスは標準の Python 辞書と同じように動作し、によって計算されたさまざまなモデル入力を保持します。
+これらのメソッド (`input_ids`、`attention_mask`...)。トークナイザーが「高速」トークナイザーである場合 (つまり、
+HuggingFace [トークナイザー ライブラリ](https://github.com/huggingface/tokenizers))、このクラスはさらに提供します
+元の文字列 (文字と単語) と
+トークンスペース (例: 指定された文字または対応する文字の範囲を構成するトークンのインデックスの取得)
+与えられたトークンに)。
+
+## PreTrainedTokenizer
+
+[[autodoc]] PreTrainedTokenizer
+ - __call__
+ - apply_chat_template
+ - batch_decode
+ - decode
+ - encode
+ - push_to_hub
+ - all
+
+## PreTrainedTokenizerFast
+
+[`PreTrainedTokenizerFast`] は [tokenizers](https://huggingface.co/docs/tokenizers) ライブラリに依存します。 🤗 トークナイザー ライブラリから取得したトークナイザーは、
+🤗 トランスに非常に簡単にロードされます。これがどのように行われるかを理解するには、[🤗 tokenizers からの tokenizers を使用する](../fast_tokenizers) ページを参照してください。
+
+[[autodoc]] PreTrainedTokenizerFast
+ - __call__
+ - apply_chat_template
+ - batch_decode
+ - decode
+ - encode
+ - push_to_hub
+ - all
+
+## BatchEncoding
+
+[[autodoc]] BatchEncoding
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/trainer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/trainer.md
new file mode 100644
index 0000000000000000000000000000000000000000..61872996ab59388fb0c3e467068502240e5fda71
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/main_classes/trainer.md
@@ -0,0 +1,727 @@
+
+
+# Trainer
+
+[`Trainer`] クラスは、ほとんどの標準的なユースケースに対して、PyTorch で機能を完全にトレーニングするための API を提供します。これは、[サンプル スクリプト](https://github.com/huggingface/transformers/tree/main/examples) のほとんどで使用されています。
+
+[`Trainer`] をインスタンス化する前に、トレーニング中にカスタマイズのすべてのポイントにアクセスするために [`TrainingArguments`] を作成します。
+
+この API は、複数の GPU/TPU での分散トレーニング、[NVIDIA Apex](https://github.com/NVIDIA/apex) および PyTorch のネイティブ AMP による混合精度をサポートします。
+
+[`Trainer`] には、上記の機能をサポートする基本的なトレーニング ループが含まれています。カスタム動作を挿入するには、それらをサブクラス化し、次のメソッドをオーバーライドします。
+
+- **get_train_dataloader** -- トレーニング データローダーを作成します。
+- **get_eval_dataloader** -- 評価用データローダーを作成します。
+- **get_test_dataloader** -- テスト データローダーを作成します。
+- **log** -- トレーニングを監視しているさまざまなオブジェクトに関する情報をログに記録します。
+- **create_optimizer_and_scheduler** -- オプティマイザと学習率スケジューラが渡されなかった場合にセットアップします。
+ 初期化。 `create_optimizer`メソッドと`create_scheduler`メソッドをサブクラス化またはオーバーライドすることもできることに注意してください。
+ 別々に。
+- **create_optimizer** -- init で渡されなかった場合にオプティマイザーをセットアップします。
+- **create_scheduler** -- init で渡されなかった場合、学習率スケジューラを設定します。
+- **compute_loss** - トレーニング入力のバッチの損失を計算します。
+- **training_step** -- トレーニング ステップを実行します。
+- **prediction_step** -- 評価/テスト ステップを実行します。
+- **evaluate** -- 評価ループを実行し、メトリクスを返します。
+- **predict** -- テスト セットの予測 (ラベルが使用可能な場合はメトリクスも含む) を返します。
+
+
+
+[`Trainer`] クラスは 🤗 Transformers モデル用に最適化されており、驚くべき動作をする可能性があります
+他の機種で使用する場合。独自のモデルで使用する場合は、次の点を確認してください。
+
+- モデルは常に [`~utils.ModelOutput`] のタプルまたはサブクラスを返します。
+- `labels` 引数が指定され、その損失が最初の値として返される場合、モデルは損失を計算できます。
+ タプルの要素 (モデルがタプルを返す場合)
+- モデルは複数のラベル引数を受け入れることができます ([`TrainingArguments`] で `label_names` を使用して、その名前を [`Trainer`] に示します) が、それらのいずれにも `"label"` という名前を付ける必要はありません。
+
+
+
+以下は、加重損失を使用するように [`Trainer`] をカスタマイズする方法の例です (不均衡なトレーニング セットがある場合に役立ちます)。
+
+```python
+from torch import nn
+from transformers import Trainer
+
+
+class CustomTrainer(Trainer):
+ def compute_loss(self, model, inputs, return_outputs=False):
+ labels = inputs.pop("labels")
+ # forward pass
+ outputs = model(**inputs)
+ logits = outputs.get("logits")
+ # compute custom loss (suppose one has 3 labels with different weights)
+ loss_fct = nn.CrossEntropyLoss(weight=torch.tensor([1.0, 2.0, 3.0], device=model.device))
+ loss = loss_fct(logits.view(-1, self.model.config.num_labels), labels.view(-1))
+ return (loss, outputs) if return_outputs else loss
+```
+
+PyTorch [`Trainer`] のトレーニング ループの動作をカスタマイズするもう 1 つの方法は、トレーニング ループの状態を検査できる [callbacks](コールバック) を使用することです (進行状況レポート、TensorBoard または他の ML プラットフォームでのログ記録など)。決定(早期停止など)。
+
+## Trainer
+
+[[autodoc]] Trainer
+ - all
+
+## Seq2SeqTrainer
+
+[[autodoc]] Seq2SeqTrainer
+ - evaluate
+ - predict
+
+## TrainingArguments
+
+[[autodoc]] TrainingArguments
+ - all
+
+## Seq2SeqTrainingArguments
+
+[[autodoc]] Seq2SeqTrainingArguments
+ - all
+
+## Checkpoints
+
+デフォルトでは、[`Trainer`] はすべてのチェックポイントを、
+[`TrainingArguments`] を使用しています。これらは、xxx を含む`checkpoint-xxx`という名前のサブフォルダーに保存されます。
+それはトレーニングの段階でした。
+
+チェックポイントからトレーニングを再開するには、次のいずれかを使用して [`Trainer.train`] を呼び出します。
+
+- `resume_from_checkpoint=True` は最新のチェックポイントからトレーニングを再開します
+- `resume_from_checkpoint=checkpoint_dir` ディレクトリ内の特定のチェックポイントからトレーニングを再開します
+ 合格した。
+
+さらに、`push_to_hub=True` を使用すると、モデル ハブにチェックポイントを簡単に保存できます。デフォルトでは、すべて
+中間チェックポイントに保存されたモデルは別のコミットに保存されますが、オプティマイザーの状態は保存されません。適応できます
+[`TrainingArguments`] の `hub-strategy` 値を次のいずれかにします。
+
+- `"checkpoint"`: 最新のチェックポイントも last-checkpoint という名前のサブフォルダーにプッシュされます。
+ `trainer.train(resume_from_checkpoint="output_dir/last-checkpoint")` を使用してトレーニングを簡単に再開します。
+- `"all_checkpoints"`: すべてのチェックポイントは、出力フォルダーに表示されるようにプッシュされます (したがって、1 つのチェックポイントが得られます)
+ 最終リポジトリ内のフォルダーごとのチェックポイント フォルダー)
+
+## Logging
+
+デフォルトでは、[`Trainer`] はメインプロセスに `logging.INFO` を使用し、レプリカがある場合には `logging.WARNING` を使用します。
+
+これらのデフォルトは、[`TrainingArguments`] の 5 つの `logging` レベルのいずれかを使用するようにオーバーライドできます。
+引数:
+
+- `log_level` - メインプロセス用
+- `log_level_replica` - レプリカ用
+
+さらに、[`TrainingArguments`] の `log_on_each_node` が `False` に設定されている場合、メイン ノードのみが
+メイン プロセスのログ レベル設定を使用すると、他のすべてのノードはレプリカのログ レベル設定を使用します。
+
+[`Trainer`] は、`transformers` のログ レベルをノードごとに個別に設定することに注意してください。
+[`Trainer.__init__`]。したがって、他の機能を利用する場合は、これをより早く設定することをお勧めします (次の例を参照)。
+[`Trainer`] オブジェクトを作成する前の `transformers` 機能。
+
+これをアプリケーションで使用する方法の例を次に示します。
+
+```python
+[...]
+logger = logging.getLogger(__name__)
+
+# Setup logging
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+)
+
+# set the main code and the modules it uses to the same log-level according to the node
+log_level = training_args.get_process_log_level()
+logger.setLevel(log_level)
+datasets.utils.logging.set_verbosity(log_level)
+transformers.utils.logging.set_verbosity(log_level)
+
+trainer = Trainer(...)
+```
+
+そして、メイン ノードと他のすべてのノードで重複する可能性が高いものを出力しないように警告するだけを表示したい場合は、
+警告: 次のように実行できます。
+
+```bash
+my_app.py ... --log_level warning --log_level_replica error
+```
+
+マルチノード環境で、各ノードのメインプロセスのログを繰り返したくない場合は、次のようにします。
+上記を次のように変更します。
+
+```bash
+my_app.py ... --log_level warning --log_level_replica error --log_on_each_node 0
+```
+
+その後、最初のノードのメイン プロセスのみが「警告」レベルでログに記録され、メイン ノード上の他のすべてのプロセスはログに記録されます。
+ノードと他のノード上のすべてのプロセスは「エラー」レベルでログに記録されます。
+
+アプリケーションをできるだけ静かにする必要がある場合は、次のようにします。
+
+```bash
+my_app.py ... --log_level error --log_level_replica error --log_on_each_node 0
+```
+
+(マルチノード環境の場合は `--log_on_each_node 0` を追加します)
+
+## Randomness
+
+[`Trainer`] によって生成されたチェックポイントから再開する場合、すべての努力がその状態を復元するために行われます。
+_python_、_numpy_、および _pytorch_ の RNG 状態は、そのチェックポイントを保存した時点と同じ状態になります。
+これにより、「停止して再開」というスタイルのトレーニングが、ノンストップトレーニングに可能な限り近づけられるはずです。
+
+ただし、さまざまなデフォルトの非決定的な pytorch 設定により、これは完全に機能しない可能性があります。フルをご希望の場合は
+決定論については、[ランダム性のソースの制御](https://pytorch.org/docs/stable/notes/randomness) を参照してください。ドキュメントで説明されているように、これらの設定の一部は
+物事を決定論的にするもの (例: `torch.backends.cudnn.deterministic`) は物事を遅くする可能性があるため、これは
+デフォルトでは実行できませんが、必要に応じて自分で有効にすることができます。
+
+## Specific GPUs Selection
+
+どの GPU をどのような順序で使用するかをプログラムに指示する方法について説明します。
+
+[`DistributedDataParallel`](https://pytorch.org/docs/stable/generated/torch.nn.Parallel.DistributedDataParallel.html) を使用して GPU のサブセットのみを使用する場合、使用する GPU の数を指定するだけです。 。たとえば、GPU が 4 つあるが、最初の 2 つを使用したい場合は、次のようにします。
+
+```bash
+torchrun --nproc_per_node=2 trainer-program.py ...
+```
+
+[`accelerate`](https://github.com/huggingface/accelerate) または [`deepspeed`](https://github.com/microsoft/DeepSpeed) がインストールされている場合は、次を使用して同じことを達成することもできます。の一つ:
+
+```bash
+accelerate launch --num_processes 2 trainer-program.py ...
+```
+
+```bash
+deepspeed --num_gpus 2 trainer-program.py ...
+```
+
+これらのランチャーを使用するために、Accelerate または [Deepspeed 統合](deepspeed) 機能を使用する必要はありません。
+
+
+これまでは、プログラムに使用する GPU の数を指示できました。次に、特定の GPU を選択し、その順序を制御する方法について説明します。
+
+次の環境変数は、使用する GPU とその順序を制御するのに役立ちます。
+
+**`CUDA_VISIBLE_DEVICES`**
+
+複数の GPU があり、そのうちの 1 つまたはいくつかの GPU だけを使用したい場合は、環境変数 `CUDA_VISIBLE_DEVICES` を使用する GPU のリストに設定します。
+
+たとえば、4 つの GPU (0、1、2、3) があるとします。物理 GPU 0 と 2 のみで実行するには、次のようにします。
+
+```bash
+CUDA_VISIBLE_DEVICES=0,2 torchrun trainer-program.py ...
+```
+
+したがって、pytorch は 2 つの GPU のみを認識し、物理 GPU 0 と 2 はそれぞれ `cuda:0` と `cuda:1` にマッピングされます。
+
+順序を変更することもできます。
+
+```bash
+CUDA_VISIBLE_DEVICES=2,0 torchrun trainer-program.py ...
+```
+
+ここでは、物理 GPU 0 と 2 がそれぞれ`cuda:1`と`cuda:0`にマッピングされています。
+
+上記の例はすべて `DistributedDataParallel` 使用パターンのものですが、同じ方法が [`DataParallel`](https://pytorch.org/docs/stable/generated/torch.nn.DataParallel.html) でも機能します。
+
+
+```bash
+CUDA_VISIBLE_DEVICES=2,0 python trainer-program.py ...
+```
+
+GPU のない環境をエミュレートするには、次のようにこの環境変数を空の値に設定するだけです。
+
+```bash
+CUDA_VISIBLE_DEVICES= python trainer-program.py ...
+```
+
+他の環境変数と同様に、これらをコマンド ラインに追加する代わりに、次のようにエクスポートすることもできます。
+
+```bash
+export CUDA_VISIBLE_DEVICES=0,2
+torchrun trainer-program.py ...
+```
+
+ただし、この方法では、以前に環境変数を設定したことを忘れて、なぜ間違った GPU が使用されているのか理解できない可能性があるため、混乱を招く可能性があります。したがって、このセクションのほとんどの例で示されているように、同じコマンド ラインで特定の実行に対してのみ環境変数を設定するのが一般的です。
+
+**`CUDA_DEVICE_ORDER`**
+
+物理デバイスの順序を制御する追加の環境変数 `CUDA_DEVICE_ORDER` があります。選択肢は次の 2 つです。
+
+1. PCIe バス ID 順 (`nvidia-smi` の順序と一致) - これがデフォルトです。
+
+```bash
+export CUDA_DEVICE_ORDER=PCI_BUS_ID
+```
+
+2. GPU コンピューティング能力順に並べる
+
+```bash
+export CUDA_DEVICE_ORDER=FASTEST_FIRST
+```
+
+ほとんどの場合、この環境変数を気にする必要はありませんが、古い GPU と新しい GPU が物理的に挿入されているため、遅い古いカードが遅くなっているように見えるような偏ったセットアップを行っている場合には、非常に役立ちます。初め。これを解決する 1 つの方法は、カードを交換することです。ただし、カードを交換できない場合 (デバイスの冷却が影響を受けた場合など)、`CUDA_DEVICE_ORDER=FASTEST_FIRST`を設定すると、常に新しい高速カードが最初に配置されます。ただし、`nvidia-smi`は依然として PCIe の順序でレポートするため、多少混乱するでしょう。
+
+順序を入れ替えるもう 1 つの解決策は、以下を使用することです。
+
+```bash
+export CUDA_VISIBLE_DEVICES=1,0
+```
+
+この例では 2 つの GPU だけを使用していますが、もちろん、コンピューターに搭載されている数の GPU にも同じことが当てはまります。
+
+また、この環境変数を設定する場合は、`~/.bashrc` ファイルまたはその他の起動設定ファイルに設定して、忘れるのが最善です。
+
+## Trainer Integrations
+
+[`Trainer`] は、トレーニングを劇的に改善する可能性のあるライブラリをサポートするように拡張されました。
+時間とはるかに大きなモデルに適合します。
+
+現在、サードパーティのソリューション [DeepSpeed](https://github.com/microsoft/DeepSpeed) および [PyTorch FSDP](https://pytorch.org/docs/stable/fsdp.html) をサポートしています。論文 [ZeRO: メモリの最適化兆パラメータ モデルのトレーニングに向けて、Samyam Rajbhandari、Jeff Rasley、Olatunji Ruwase、Yuxiong He 著](https://arxiv.org/abs/1910.02054)。
+
+この提供されるサポートは、この記事の執筆時点では新しくて実験的なものです。 DeepSpeed と PyTorch FSDP のサポートはアクティブであり、それに関する問題は歓迎しますが、FairScale 統合は PyTorch メインに統合されているため、もうサポートしていません ([PyTorch FSDP 統合](#pytorch-fully-sharded-data-parallel))
+
+`を介して渡されます。それは、次のいずれかの場所です。
+ FSDP json 構成ファイル (例: `fsdp_config.json`)、またはすでにロードされている json ファイルを `dict` として使用します。
+ - 自動ラッピングが有効な場合は、トランスベースの自動ラップ ポリシーまたはサイズ ベースの自動ラップ ポリシーを使用できます。
+ - トランスフォーマーベースの自動ラップポリシーの場合、構成ファイルで `fsdp_transformer_layer_cls_to_wrap` を指定することをお勧めします。指定しない場合、使用可能な場合、デフォルト値は `model._no_split_modules` になります。
+ これは、ラップするトランスフォーマー層クラス名のリスト (大文字と小文字を区別) を指定します (例: [`BertLayer`]、[`GPTJBlock`]、[`T5Block`] ...)。
+ 重みを共有するサブモジュール (埋め込み層など) が異なる FSDP ラップされたユニットにならないようにする必要があるため、これは重要です。
+ このポリシーを使用すると、マルチヘッド アテンションとそれに続くいくつかの MLP レイヤーを含むブロックごとにラッピングが発生します。
+ 共有埋め込みを含む残りの層は、同じ最も外側の FSDP ユニットにラップされるのが便利です。
+ したがって、トランスベースのモデルにはこれを使用してください。
+ - サイズベースの自動ラップポリシーの場合は、設定ファイルに`fsdp_min_num_params`を追加してください。
+ 自動ラッピングのための FSDP のパラメータの最小数を指定します。
+ - 設定ファイルで `fsdp_backward_prefetch` を指定できるようになりました。次のパラメータのセットをいつプリフェッチするかを制御します。
+ `backward_pre` と `backward_pos` が利用可能なオプションです。
+ 詳細については、`torch.distributed.fsdp.full_sharded_data_Parallel.BackwardPrefetch`を参照してください。
+ - 設定ファイルで `fsdp_forward_prefetch` を指定できるようになりました。次のパラメータのセットをいつプリフェッチするかを制御します。
+ `True`の場合、FSDP はフォワード パスでの実行中に、次に来るオールギャザーを明示的にプリフェッチします。
+ - 設定ファイルで `limit_all_gathers` を指定できるようになりました。
+ `True`の場合、FSDP は CPU スレッドを明示的に同期して、実行中のオールギャザが多すぎるのを防ぎます。
+ - `activation_checkpointing`を設定ファイルで指定できるようになりました。
+ `True`の場合、FSDP アクティベーション チェックポイントは、FSDP のアクティベーションをクリアすることでメモリ使用量を削減する手法です。
+ 特定のレイヤーを処理し、バックワード パス中にそれらを再計算します。事実上、これは余分な計算時間を犠牲にします
+ メモリ使用量を削減します。
+
+**注意すべき注意点がいくつかあります**
+- これは `generate` と互換性がないため、 `--predict_with_generate` とも互換性がありません
+ すべての seq2seq/clm スクリプト (翻訳/要約/clm など)。
+ 問題 [#21667](https://github.com/huggingface/transformers/issues/21667) を参照してください。
+
+### PyTorch/XLA Fully Sharded Data parallel
+
+TPU ユーザーの皆様に朗報です。 PyTorch/XLA は FSDP をサポートするようになりました。
+最新の Fully Sharded Data Parallel (FSDP) トレーニングがすべてサポートされています。
+詳細については、[FSDP を使用した Cloud TPU での PyTorch モデルのスケーリング](https://pytorch.org/blog/scaling-pytorch-models-on-cloud-tpus-with-fsdp/) および [PyTorch/XLA 実装 を参照してください。 FSDP の](https://github.com/pytorch/xla/tree/master/torch_xla/distributed/fsdp)
+必要なのは、設定を通じて有効にすることだけです。
+
+**FSDP サポートに必要な PyTorch/XLA バージョン**: >=2.0
+
+**使用法**:
+
+`--fsdp "full shard"` を、`--fsdp_config ` に加えられる次の変更とともに渡します。
+- PyTorch/XLA FSDP を有効にするには、`xla`を`True`に設定する必要があります。
+- `xla_fsdp_settings` 値は、XLA FSDP ラッピング パラメータを格納する辞書です。
+ オプションの完全なリストについては、[こちら](
+ https://github.com/pytorch/xla/blob/master/torch_xla/distributed/fsdp/xla_full_sharded_data_Parallel.py)。
+- `xla_fsdp_grad_ckpt`。 `True`の場合、ネストされた XLA FSDP でラップされた各レイヤー上で勾配チェックポイントを使用します。
+ この設定は、xla フラグが true に設定されており、自動ラッピング ポリシーが指定されている場合にのみ使用できます。
+ `fsdp_min_num_params` または `fsdp_transformer_layer_cls_to_wrap`。
+- トランスフォーマー ベースの自動ラップ ポリシーまたはサイズ ベースの自動ラップ ポリシーのいずれかを使用できます。
+ - トランスフォーマーベースの自動ラップポリシーの場合、構成ファイルで `fsdp_transformer_layer_cls_to_wrap` を指定することをお勧めします。指定しない場合、使用可能な場合、デフォルト値は `model._no_split_modules` になります。
+ これは、ラップするトランスフォーマー層クラス名のリスト (大文字と小文字を区別) を指定します (例: [`BertLayer`]、[`GPTJBlock`]、[`T5Block`] ...)。
+ 重みを共有するサブモジュール (埋め込み層など) が異なる FSDP ラップされたユニットにならないようにする必要があるため、これは重要です。
+ このポリシーを使用すると、マルチヘッド アテンションとそれに続くいくつかの MLP レイヤーを含むブロックごとにラッピングが発生します。
+ 共有埋め込みを含む残りの層は、同じ最も外側の FSDP ユニットにラップされるのが便利です。
+ したがって、トランスベースのモデルにはこれを使用してください。
+ - サイズベースの自動ラップポリシーの場合は、設定ファイルに`fsdp_min_num_params`を追加してください。
+ 自動ラッピングのための FSDP のパラメータの最小数を指定します。
+
+### Using Trainer for accelerated PyTorch Training on Mac
+
+PyTorch v1.12 リリースにより、開発者と研究者は Apple シリコン GPU を利用してモデル トレーニングを大幅に高速化できます。
+これにより、プロトタイピングや微調整などの機械学習ワークフローを Mac 上でローカルで実行できるようになります。
+PyTorch のバックエンドとしての Apple の Metal Performance Shaders (MPS) はこれを可能にし、新しい `"mps"` デバイス経由で使用できます。
+これにより、計算グラフとプリミティブが MPS Graph フレームワークと MPS によって提供される調整されたカーネルにマッピングされます。
+詳細については、公式ドキュメント [Mac での Accelerated PyTorch Training の紹介](https://pytorch.org/blog/introducing-accelerated-pytorch-training-on-mac/) を参照してください。
+および [MPS バックエンド](https://pytorch.org/docs/stable/notes/mps.html)。
+
+
+
+MacOS マシンに PyTorch >= 1.13 (執筆時点ではナイトリー バージョン) をインストールすることを強くお勧めします。
+トランスベースのモデルのモデルの正確性とパフォーマンスの向上に関連する主要な修正が行われています。
+詳細については、https://github.com/pytorch/pytorch/issues/82707 を参照してください。
+
+
+
+**Apple Silicon チップを使用したトレーニングと推論の利点**
+
+1. ユーザーがローカルで大規模なネットワークやバッチ サイズをトレーニングできるようにします
+2. ユニファイド メモリ アーキテクチャにより、データ取得の遅延が短縮され、GPU がメモリ ストア全体に直接アクセスできるようになります。
+したがって、エンドツーエンドのパフォーマンスが向上します。
+3. クラウドベースの開発に関連するコストや追加のローカル GPU の必要性を削減します。
+
+**前提条件**: mps サポートを備えたトーチをインストールするには、
+この素晴らしいメディア記事 [GPU アクセラレーションが M1 Mac の PyTorch に登場](https://medium.com/towards-data-science/gpu-acceleration-comes-to-pytorch-on-m1-macs-195c399efcc1) に従ってください。 。
+
+**使用法**:
+`mps` デバイスは、`cuda` デバイスが使用される方法と同様に利用可能な場合、デフォルトで使用されます。
+したがって、ユーザーによるアクションは必要ありません。
+たとえば、以下のコマンドを使用して、Apple Silicon GPU を使用して公式の Glue テキスト分類タスクを (ルート フォルダーから) 実行できます。
+
+```bash
+export TASK_NAME=mrpc
+
+python examples/pytorch/text-classification/run_glue.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/ \
+ --overwrite_output_dir
+```
+
+**注意すべきいくつかの注意事項**
+
+1. 一部の PyTorch 操作は mps に実装されていないため、エラーがスローされます。
+これを回避する 1 つの方法は、環境変数 `PYTORCH_ENABLE_MPS_FALLBACK=1` を設定することです。
+これらの操作では CPU にフォールバックします。ただし、それでも UserWarning がスローされます。
+2. 分散セットアップ`gloo`および`nccl`は、`mps`デバイスでは動作しません。
+これは、現在「mps」デバイス タイプの単一 GPU のみを使用できることを意味します。
+
+最後に、覚えておいてください。 🤗 `Trainer` は MPS バックエンドのみを統合するため、
+MPS バックエンドの使用に関して問題や質問がある場合は、
+[PyTorch GitHub](https://github.com/pytorch/pytorch/issues) に問題を提出してください。
+
+## Using Accelerate Launcher with Trainer
+
+加速してトレーナーにパワーを与えましょう。ユーザーが期待することに関しては、次のとおりです。
+- トレーナー引数に対して FSDP、DeepSpeed などのトレーナー インテレーションを変更せずに使用し続けることができます。
+- トレーナーで Accelerate Launcher を使用できるようになりました (推奨)。
+
+トレーナーで Accelerate Launcher を使用する手順:
+1. 🤗 Accelerate がインストールされていることを確認してください。Accelerate がないと `Trainer` を使用することはできません。そうでない場合は、`pip install accelerate`してください。 Accelerate のバージョンを更新する必要がある場合もあります: `pip install activate --upgrade`
+2. `accelerate config`を実行し、アンケートに記入します。以下は加速設定の例です。
+ a. DDP マルチノード マルチ GPU 構成:
+ ```yaml
+ compute_environment: LOCAL_MACHINE
+ distributed_type: MULTI_GPU
+ downcast_bf16: 'no'
+ gpu_ids: all
+ machine_rank: 0 #change rank as per the node
+ main_process_ip: 192.168.20.1
+ main_process_port: 9898
+ main_training_function: main
+ mixed_precision: fp16
+ num_machines: 2
+ num_processes: 8
+ rdzv_backend: static
+ same_network: true
+ tpu_env: []
+ tpu_use_cluster: false
+ tpu_use_sudo: false
+ use_cpu: false
+ ```
+
+ b. FSDP config:
+ ```yaml
+ compute_environment: LOCAL_MACHINE
+ distributed_type: FSDP
+ downcast_bf16: 'no'
+ fsdp_config:
+ fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
+ fsdp_backward_prefetch_policy: BACKWARD_PRE
+ fsdp_forward_prefetch: true
+ fsdp_offload_params: false
+ fsdp_sharding_strategy: 1
+ fsdp_state_dict_type: FULL_STATE_DICT
+ fsdp_sync_module_states: true
+ fsdp_transformer_layer_cls_to_wrap: BertLayer
+ fsdp_use_orig_params: true
+ machine_rank: 0
+ main_training_function: main
+ mixed_precision: bf16
+ num_machines: 1
+ num_processes: 2
+ rdzv_backend: static
+ same_network: true
+ tpu_env: []
+ tpu_use_cluster: false
+ tpu_use_sudo: false
+ use_cpu: false
+ ```
+ c.ファイルを指す DeepSpeed 構成:
+ ```yaml
+ compute_environment: LOCAL_MACHINE
+ deepspeed_config:
+ deepspeed_config_file: /home/user/configs/ds_zero3_config.json
+ zero3_init_flag: true
+ distributed_type: DEEPSPEED
+ downcast_bf16: 'no'
+ machine_rank: 0
+ main_training_function: main
+ num_machines: 1
+ num_processes: 4
+ rdzv_backend: static
+ same_network: true
+ tpu_env: []
+ tpu_use_cluster: false
+ tpu_use_sudo: false
+ use_cpu: false
+ ```
+
+ d.加速プラグインを使用した DeepSpeed 構成:
+
+ ```yaml
+ compute_environment: LOCAL_MACHINE
+ deepspeed_config:
+ gradient_accumulation_steps: 1
+ gradient_clipping: 0.7
+ offload_optimizer_device: cpu
+ offload_param_device: cpu
+ zero3_init_flag: true
+ zero_stage: 2
+ distributed_type: DEEPSPEED
+ downcast_bf16: 'no'
+ machine_rank: 0
+ main_training_function: main
+ mixed_precision: bf16
+ num_machines: 1
+ num_processes: 4
+ rdzv_backend: static
+ same_network: true
+ tpu_env: []
+ tpu_use_cluster: false
+ tpu_use_sudo: false
+ use_cpu: false
+ ```
+
+3. 加速設定またはランチャー引数によって上記で処理された引数以外の引数を使用して、トレーナー スクリプトを実行します。
+以下は、上記の FSDP 構成で`accelerate launcher`を使用して`run_glue.py`を実行する例です。
+
+```bash
+cd transformers
+
+accelerate launch \
+./examples/pytorch/text-classification/run_glue.py \
+--model_name_or_path google-bert/bert-base-cased \
+--task_name $TASK_NAME \
+--do_train \
+--do_eval \
+--max_seq_length 128 \
+--per_device_train_batch_size 16 \
+--learning_rate 5e-5 \
+--num_train_epochs 3 \
+--output_dir /tmp/$TASK_NAME/ \
+--overwrite_output_dir
+```
+
+4. `accelerate launch`するための cmd 引数を直接使用することもできます。上の例は次のようにマッピングされます。
+
+```bash
+cd transformers
+
+accelerate launch --num_processes=2 \
+--use_fsdp \
+--mixed_precision=bf16 \
+--fsdp_auto_wrap_policy=TRANSFORMER_BASED_WRAP \
+--fsdp_transformer_layer_cls_to_wrap="BertLayer" \
+--fsdp_sharding_strategy=1 \
+--fsdp_state_dict_type=FULL_STATE_DICT \
+./examples/pytorch/text-classification/run_glue.py
+--model_name_or_path google-bert/bert-base-cased \
+--task_name $TASK_NAME \
+--do_train \
+--do_eval \
+--max_seq_length 128 \
+--per_device_train_batch_size 16 \
+--learning_rate 5e-5 \
+--num_train_epochs 3 \
+--output_dir /tmp/$TASK_NAME/ \
+--overwrite_output_dir
+```
+
+詳細については、🤗 Accelerate CLI ガイドを参照してください: [🤗 Accelerate スクリプトの起動](https://huggingface.co/docs/accelerate/basic_tutorials/launch)。
+
+移動されたセクション:
+
+[ DeepSpeed Installation Deployment with multiple GPUs Deployment with one GPU Deployment in Notebooks Configuration Passing Configuration Shared Configuration ZeRO ZeRO-2 Config ZeRO-3 Config NVMe Support ZeRO-2 vs ZeRO-3 Performance ZeRO-2 Example ZeRO-3 Example Optimizer Scheduler fp32 Precision Automatic Mixed Precision Batch Size Gradient Accumulation Gradient Clipping Getting The Model Weights Out
+
+
+## AlbertModel
+
+[[autodoc]] AlbertModel
+ - forward
+
+## AlbertForPreTraining
+
+[[autodoc]] AlbertForPreTraining
+ - forward
+
+## AlbertForMaskedLM
+
+[[autodoc]] AlbertForMaskedLM
+ - forward
+
+## AlbertForSequenceClassification
+
+[[autodoc]] AlbertForSequenceClassification
+ - forward
+
+## AlbertForMultipleChoice
+
+[[autodoc]] AlbertForMultipleChoice
+
+## AlbertForTokenClassification
+
+[[autodoc]] AlbertForTokenClassification
+ - forward
+
+## AlbertForQuestionAnswering
+
+[[autodoc]] AlbertForQuestionAnswering
+ - forward
+
+
+
+
+
+## TFAlbertModel
+
+[[autodoc]] TFAlbertModel
+ - call
+
+## TFAlbertForPreTraining
+
+[[autodoc]] TFAlbertForPreTraining
+ - call
+
+## TFAlbertForMaskedLM
+
+[[autodoc]] TFAlbertForMaskedLM
+ - call
+
+## TFAlbertForSequenceClassification
+
+[[autodoc]] TFAlbertForSequenceClassification
+ - call
+
+## TFAlbertForMultipleChoice
+
+[[autodoc]] TFAlbertForMultipleChoice
+ - call
+
+## TFAlbertForTokenClassification
+
+[[autodoc]] TFAlbertForTokenClassification
+ - call
+
+## TFAlbertForQuestionAnswering
+
+[[autodoc]] TFAlbertForQuestionAnswering
+ - call
+
+
+
+
+## FlaxAlbertModel
+
+[[autodoc]] FlaxAlbertModel
+ - __call__
+
+## FlaxAlbertForPreTraining
+
+[[autodoc]] FlaxAlbertForPreTraining
+ - __call__
+
+## FlaxAlbertForMaskedLM
+
+[[autodoc]] FlaxAlbertForMaskedLM
+ - __call__
+
+## FlaxAlbertForSequenceClassification
+
+[[autodoc]] FlaxAlbertForSequenceClassification
+ - __call__
+
+## FlaxAlbertForMultipleChoice
+
+[[autodoc]] FlaxAlbertForMultipleChoice
+ - __call__
+
+## FlaxAlbertForTokenClassification
+
+[[autodoc]] FlaxAlbertForTokenClassification
+ - __call__
+
+## FlaxAlbertForQuestionAnswering
+
+[[autodoc]] FlaxAlbertForQuestionAnswering
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/align.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/align.md
new file mode 100644
index 0000000000000000000000000000000000000000..84496e605def922dcc1e11258e07b566d12fadec
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/align.md
@@ -0,0 +1,104 @@
+
+
+# ALIGN
+
+## 概要
+
+ALIGNモデルは、「[Scaling Up Visual and Vision-Language Representation Learning With Noisy Text Supervision](https://arxiv.org/abs/2102.05918)」という論文でChao Jia、Yinfei Yang、Ye Xia、Yi-Ting Chen、Zarana Parekh、Hieu Pham、Quoc V. Le、Yunhsuan Sung、Zhen Li、Tom Duerigによって提案されました。ALIGNはマルチモーダルな視覚言語モデルです。これは画像とテキストの類似度や、ゼロショット画像分類に使用できます。ALIGNは[EfficientNet](efficientnet)を視覚エンコーダーとして、[BERT](bert)をテキストエンコーダーとして搭載したデュアルエンコーダー構造を特徴とし、対照学習によって視覚とテキストの表現を整合させることを学びます。それまでの研究とは異なり、ALIGNは巨大でノイジーなデータセットを活用し、コーパスのスケールを利用して単純な方法ながら最先端の表現を達成できることを示しています。
+
+論文の要旨は以下の通りです:
+
+*事前学習された表現は、多くの自然言語処理(NLP)および知覚タスクにとって重要になっています。NLPにおける表現学習は、人間のアノテーションのない生のテキストでの学習へと移行していますが、視覚および視覚言語の表現は依然として精巧な学習データセットに大きく依存しており、これは高価であったり専門知識を必要としたりします。視覚アプリケーションの場合、ImageNetやOpenImagesのような明示的なクラスラベルを持つデータセットを使用して学習されることがほとんどです。視覚言語の場合、Conceptual Captions、MSCOCO、CLIPなどの人気のあるデータセットはすべて、それぞれ無視できないデータ収集(およびクリーニング)プロセスを含みます。このコストのかかるキュレーションプロセスはデータセットのサイズを制限し、訓練されたモデルのスケーリングを妨げます。本論文では、Conceptual Captionsデータセットの高価なフィルタリングや後処理ステップなしで得られた、10億を超える画像alt-textペアのノイズの多いデータセットを活用します。シンプルなデュアルエンコーダーアーキテクチャは、対照損失を使用して画像とテキストペアの視覚的および言語的表現を整合させることを学習します。我々は、コーパスの規模がそのノイズを補い、このような単純な学習スキームでも最先端の表現につながることを示します。我々の視覚表現は、ImageNetやVTABなどの分類タスクへの転移において強力な性能を発揮します。整合した視覚的および言語的表現は、ゼロショット画像分類を可能にし、また、より洗練されたクロスアテンションモデルと比較しても、Flickr30KおよびMSCOCO画像テキスト検索ベンチマークにおいて新たな最先端の結果を達成します。また、これらの表現は、複雑なテキストおよびテキスト+画像のクエリを用いたクロスモーダル検索を可能にします。*
+
+このモデルは[Alara Dirik](https://huggingface.co/adirik)により提供されました。
+オリジナルのコードは公開されておらず、この実装は元論文に基づいたKakao Brainの実装をベースにしています。
+
+## 使用例
+
+ALIGNはEfficientNetを使用して視覚的特徴を、BERTを使用してテキスト特徴を取得します。テキストと視覚の両方の特徴は、同一の次元を持つ潜在空間に射影されます。射影された画像とテキスト特徴間のドット積が類似度スコアとして使用されます。
+
+[`AlignProcessor`]は、テキストのエンコードと画像の前処理を両方行うために、[`EfficientNetImageProcessor`]と[`BertTokenizer`]を単一のインスタンスにラップします。以下の例は、[`AlignProcessor`]と[`AlignModel`]を使用して画像-テキスト類似度スコアを取得する方法を示しています。
+
+```python
+import requests
+import torch
+from PIL import Image
+from transformers import AlignProcessor, AlignModel
+
+processor = AlignProcessor.from_pretrained("kakaobrain/align-base")
+model = AlignModel.from_pretrained("kakaobrain/align-base")
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+candidate_labels = ["an image of a cat", "an image of a dog"]
+
+inputs = processor(text=candidate_labels, images=image, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+# this is the image-text similarity score
+logits_per_image = outputs.logits_per_image
+
+# we can take the softmax to get the label probabilities
+probs = logits_per_image.softmax(dim=1)
+print(probs)
+```
+
+## 参考資料
+
+ALIGNの使用を開始するのに役立つ公式のHugging Faceとコミュニティ(🌎で示されている)の参考資料の一覧です。
+
+- [ALIGNとCOYO-700Mデータセット](https://huggingface.co/blog/vit-align)に関するブログ投稿。
+- ゼロショット画像分類[デモ](https://huggingface.co/spaces/adirik/ALIGN-zero-shot-image-classification)。
+- `kakaobrain/align-base` モデルの[モデルカード](https://huggingface.co/kakaobrain/align-base)。
+
+ここに参考資料を提出したい場合は、気兼ねなくPull Requestを開いてください。私たちはそれをレビューいたします!参考資料は、既存のものを複製するのではなく、何か新しいことを示すことが理想的です。
+
+## AlignConfig
+
+[[autodoc]] AlignConfig
+ - from_text_vision_configs
+
+## AlignTextConfig
+
+[[autodoc]] AlignTextConfig
+
+## AlignVisionConfig
+
+[[autodoc]] AlignVisionConfig
+
+## AlignProcessor
+
+[[autodoc]] AlignProcessor
+
+## AlignModel
+
+[[autodoc]] AlignModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## AlignTextModel
+
+[[autodoc]] AlignTextModel
+ - forward
+
+## AlignVisionModel
+
+[[autodoc]] AlignVisionModel
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/altclip.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/altclip.md
new file mode 100644
index 0000000000000000000000000000000000000000..87cf6cc17d6a0becd1c74cc161c3d3e3365d0b18
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/altclip.md
@@ -0,0 +1,97 @@
+
+
+# AltCLIP
+
+## 概要
+
+
+AltCLIPモデルは、「[AltCLIP: Altering the Language Encoder in CLIP for Extended Language Capabilities](https://arxiv.org/abs/2211.06679v2)」という論文でZhongzhi Chen、Guang Liu、Bo-Wen Zhang、Fulong Ye、Qinghong Yang、Ledell Wuによって提案されました。AltCLIP(CLIPの言語エンコーダーの代替)は、様々な画像-テキストペアおよびテキスト-テキストペアでトレーニングされたニューラルネットワークです。CLIPのテキストエンコーダーを事前学習済みの多言語テキストエンコーダーXLM-Rに置き換えることで、ほぼ全てのタスクでCLIPに非常に近い性能を得られ、オリジナルのCLIPの能力を多言語理解などに拡張しました。
+
+論文の要旨は以下の通りです:
+
+*この研究では、強力なバイリンガルマルチモーダル表現モデルを訓練するための概念的に単純で効果的な方法を提案します。OpenAIによってリリースされたマルチモーダル表現モデルCLIPから開始し、そのテキストエンコーダを事前学習済みの多言語テキストエンコーダXLM-Rに交換し、教師学習と対照学習からなる2段階のトレーニングスキーマを用いて言語と画像の表現を整合させました。幅広いタスクの評価を通じて、我々の方法を検証します。ImageNet-CN、Flicker30k-CN、COCO-CNを含む多くのタスクで新たな最先端の性能を達成しました。さらに、ほぼすべてのタスクでCLIPに非常に近い性能を得ており、これはCLIPのテキストエンコーダを変更するだけで、多言語理解などの拡張を実現できることを示唆しています。*
+
+このモデルは[jongjyh](https://huggingface.co/jongjyh)により提供されました。
+
+## 使用上のヒントと使用例
+
+AltCLIPの使用方法はCLIPに非常に似ています。CLIPとの違いはテキストエンコーダーにあります。私たちはカジュアルアテンションではなく双方向アテンションを使用し、XLM-Rの[CLS]トークンをテキスト埋め込みを表すものとして取ることに留意してください。
+
+AltCLIPはマルチモーダルな視覚言語モデルです。これは画像とテキストの類似度や、ゼロショット画像分類に使用できます。AltCLIPはViTのようなTransformerを使用して視覚的特徴を、双方向言語モデルを使用してテキスト特徴を取得します。テキストと視覚の両方の特徴は、同一の次元を持つ潜在空間に射影されます。射影された画像とテキスト特徴間のドット積が類似度スコアとして使用されます。
+
+Transformerエンコーダーに画像を与えるには、各画像を固定サイズの重複しないパッチの系列に分割し、それらを線形に埋め込みます。画像全体を表現するための[CLS]トークンが追加されます。著者は絶対位置埋め込みも追加し、結果として得られるベクトルの系列を標準的なTransformerエンコーダーに供給します。[`CLIPImageProcessor`]を使用して、モデルのために画像のサイズ変更(または拡大縮小)と正規化を行うことができます。
+
+[`AltCLIPProcessor`]は、テキストのエンコードと画像の前処理を両方行うために、[`CLIPImageProcessor`]と[`XLMRobertaTokenizer`]を単一のインスタンスにラップします。以下の例は、[`AltCLIPProcessor`]と[`AltCLIPModel`]を使用して画像-テキスト類似スコアを取得する方法を示しています。
+
+```python
+>>> from PIL import Image
+>>> import requests
+
+>>> from transformers import AltCLIPModel, AltCLIPProcessor
+
+>>> model = AltCLIPModel.from_pretrained("BAAI/AltCLIP")
+>>> processor = AltCLIPProcessor.from_pretrained("BAAI/AltCLIP")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> inputs = processor(text=["a photo of a cat", "a photo of a dog"], images=image, return_tensors="pt", padding=True)
+
+>>> outputs = model(**inputs)
+>>> logits_per_image = outputs.logits_per_image # this is the image-text similarity score
+>>> probs = logits_per_image.softmax(dim=1) # we can take the softmax to get the label probabilities
+```
+
+
+
+このモデルは`CLIPModel`をベースにしており、オリジナルの[CLIP](clip)と同じように使用してください。
+
+
+
+## AltCLIPConfig
+
+[[autodoc]] AltCLIPConfig
+ - from_text_vision_configs
+
+## AltCLIPTextConfig
+
+[[autodoc]] AltCLIPTextConfig
+
+## AltCLIPVisionConfig
+
+[[autodoc]] AltCLIPVisionConfig
+
+## AltCLIPProcessor
+
+[[autodoc]] AltCLIPProcessor
+
+## AltCLIPModel
+
+[[autodoc]] AltCLIPModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## AltCLIPTextModel
+
+[[autodoc]] AltCLIPTextModel
+ - forward
+
+## AltCLIPVisionModel
+
+[[autodoc]] AltCLIPVisionModel
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/audio-spectrogram-transformer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/audio-spectrogram-transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..a5107b14f83a9800a2f68ac910161d3c646d7de5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/audio-spectrogram-transformer.md
@@ -0,0 +1,69 @@
+
+
+# Audio Spectrogram Transformer
+
+## 概要
+
+Audio Spectrogram Transformerモデルは、[AST: Audio Spectrogram Transformer](https://arxiv.org/abs/2104.01778)という論文でYuan Gong、Yu-An Chung、James Glassによって提案されました。これは、音声を画像(スペクトログラム)に変換することで、音声に[Vision Transformer](vit)を適用します。このモデルは音声分類において最先端の結果を得ています。
+
+論文の要旨は以下の通りです:
+
+*過去10年間で、畳み込みニューラルネットワーク(CNN)は、音声スペクトログラムから対応するラベルへの直接的なマッピングを学習することを目指す、エンドツーエンドの音声分類モデルの主要な構成要素として広く採用されてきました。長距離のグローバルなコンテキストをより良く捉えるため、最近の傾向として、CNNの上にセルフアテンション機構を追加し、CNN-アテンションハイブリッドモデルを形成することがあります。しかし、CNNへの依存が必要かどうか、そして純粋にアテンションに基づくニューラルネットワークだけで音声分類において良いパフォーマンスを得ることができるかどうかは明らかではありません。本論文では、これらの問いに答えるため、音声分類用では最初の畳み込みなしで純粋にアテンションベースのモデルであるAudio Spectrogram Transformer(AST)を紹介します。我々はASTを様々なオーディオ分類ベンチマークで評価し、AudioSetで0.485 mAP、ESC-50で95.6%の正解率、Speech Commands V2で98.1%の正解率という新たな最先端の結果を達成しました。*
+
+ Audio Spectrogram Transformerのアーキテクチャ。元論文 より抜粋。
+
+このモデルは[nielsr](https://huggingface.co/nielsr)より提供されました。
+オリジナルのコードは[こちら](https://github.com/YuanGongND/ast)で見ることができます。
+
+## 使用上のヒント
+
+- 独自のデータセットでAudio Spectrogram Transformer(AST)をファインチューニングする場合、入力の正規化(入力の平均を0、標準偏差を0.5にすること)処理することが推奨されます。[`ASTFeatureExtractor`]はこれを処理します。デフォルトではAudioSetの平均と標準偏差を使用していることに注意してください。著者が下流のデータセットの統計をどのように計算しているかは、[`ast/src/get_norm_stats.py`](https://github.com/YuanGongND/ast/blob/master/src/get_norm_stats.py)で確認することができます。
+- ASTは低い学習率が必要であり 著者は[PSLA論文](https://arxiv.org/abs/2102.01243)で提案されたCNNモデルに比べて10倍小さい学習率を使用しています)、素早く収束するため、タスクに適した学習率と学習率スケジューラーを探すことをお勧めします。
+
+## 参考資料
+
+Audio Spectrogram Transformerの使用を開始するのに役立つ公式のHugging Faceおよびコミュニティ(🌎で示されている)の参考資料の一覧です。
+
+
+
+あなたの`NewModelConfig`が[`~transformers.PretrainedConfig`]のサブクラスである場合、その`model_type`属性がコンフィグを登録するときに使用するキー(ここでは`"new-model"`)と同じに設定されていることを確認してください。
+
+同様に、あなたの`NewModel`が[`PreTrainedModel`]のサブクラスである場合、その`config_class`属性がモデルを登録する際に使用するクラス(ここでは`NewModelConfig`)と同じに設定されていることを確認してください。
+
+
+
+## AutoConfig
+
+[[autodoc]] AutoConfig
+
+## AutoTokenizer
+
+[[autodoc]] AutoTokenizer
+
+## AutoFeatureExtractor
+
+[[autodoc]] AutoFeatureExtractor
+
+## AutoImageProcessor
+
+[[autodoc]] AutoImageProcessor
+
+## AutoProcessor
+
+[[autodoc]] AutoProcessor
+
+## Generic model classes
+
+以下の自動クラスは、特定のヘッドを持たないベースモデルクラスをインスタンス化するために利用可能です。
+
+### AutoModel
+
+[[autodoc]] AutoModel
+
+### TFAutoModel
+
+[[autodoc]] TFAutoModel
+
+### FlaxAutoModel
+
+[[autodoc]] FlaxAutoModel
+
+## Generic pretraining classes
+
+以下の自動クラスは、事前学習ヘッドを持つモデルをインスタンス化するために利用可能です。
+
+### AutoModelForPreTraining
+
+[[autodoc]] AutoModelForPreTraining
+
+### TFAutoModelForPreTraining
+
+[[autodoc]] TFAutoModelForPreTraining
+
+### FlaxAutoModelForPreTraining
+
+[[autodoc]] FlaxAutoModelForPreTraining
+
+## Natural Language Processing
+
+以下の自動クラスは、次の自然言語処理タスクに利用可能です。
+
+### AutoModelForCausalLM
+
+[[autodoc]] AutoModelForCausalLM
+
+### TFAutoModelForCausalLM
+
+[[autodoc]] TFAutoModelForCausalLM
+
+### FlaxAutoModelForCausalLM
+
+[[autodoc]] FlaxAutoModelForCausalLM
+
+### AutoModelForMaskedLM
+
+[[autodoc]] AutoModelForMaskedLM
+
+### TFAutoModelForMaskedLM
+
+[[autodoc]] TFAutoModelForMaskedLM
+
+### FlaxAutoModelForMaskedLM
+
+[[autodoc]] FlaxAutoModelForMaskedLM
+
+### AutoModelForMaskGeneration
+
+[[autodoc]] AutoModelForMaskGeneration
+
+### TFAutoModelForMaskGeneration
+
+[[autodoc]] TFAutoModelForMaskGeneration
+
+### AutoModelForSeq2SeqLM
+
+[[autodoc]] AutoModelForSeq2SeqLM
+
+### TFAutoModelForSeq2SeqLM
+
+[[autodoc]] TFAutoModelForSeq2SeqLM
+
+### FlaxAutoModelForSeq2SeqLM
+
+[[autodoc]] FlaxAutoModelForSeq2SeqLM
+
+### AutoModelForSequenceClassification
+
+[[autodoc]] AutoModelForSequenceClassification
+
+### TFAutoModelForSequenceClassification
+
+[[autodoc]] TFAutoModelForSequenceClassification
+
+### FlaxAutoModelForSequenceClassification
+
+[[autodoc]] FlaxAutoModelForSequenceClassification
+
+### AutoModelForMultipleChoice
+
+[[autodoc]] AutoModelForMultipleChoice
+
+### TFAutoModelForMultipleChoice
+
+[[autodoc]] TFAutoModelForMultipleChoice
+
+### FlaxAutoModelForMultipleChoice
+
+[[autodoc]] FlaxAutoModelForMultipleChoice
+
+### AutoModelForNextSentencePrediction
+
+[[autodoc]] AutoModelForNextSentencePrediction
+
+### TFAutoModelForNextSentencePrediction
+
+[[autodoc]] TFAutoModelForNextSentencePrediction
+
+### FlaxAutoModelForNextSentencePrediction
+
+[[autodoc]] FlaxAutoModelForNextSentencePrediction
+
+### AutoModelForTokenClassification
+
+[[autodoc]] AutoModelForTokenClassification
+
+### TFAutoModelForTokenClassification
+
+[[autodoc]] TFAutoModelForTokenClassification
+
+### FlaxAutoModelForTokenClassification
+
+[[autodoc]] FlaxAutoModelForTokenClassification
+
+### AutoModelForQuestionAnswering
+
+[[autodoc]] AutoModelForQuestionAnswering
+
+### TFAutoModelForQuestionAnswering
+
+[[autodoc]] TFAutoModelForQuestionAnswering
+
+### FlaxAutoModelForQuestionAnswering
+
+[[autodoc]] FlaxAutoModelForQuestionAnswering
+
+### AutoModelForTextEncoding
+
+[[autodoc]] AutoModelForTextEncoding
+
+### TFAutoModelForTextEncoding
+
+[[autodoc]] TFAutoModelForTextEncoding
+
+## Computer vision
+
+以下の自動クラスは、次のコンピュータービジョンタスクに利用可能です。
+
+### AutoModelForDepthEstimation
+
+[[autodoc]] AutoModelForDepthEstimation
+
+### AutoModelForImageClassification
+
+[[autodoc]] AutoModelForImageClassification
+
+### TFAutoModelForImageClassification
+
+[[autodoc]] TFAutoModelForImageClassification
+
+### FlaxAutoModelForImageClassification
+
+[[autodoc]] FlaxAutoModelForImageClassification
+
+### AutoModelForVideoClassification
+
+[[autodoc]] AutoModelForVideoClassification
+
+### AutoModelForMaskedImageModeling
+
+[[autodoc]] AutoModelForMaskedImageModeling
+
+### TFAutoModelForMaskedImageModeling
+
+[[autodoc]] TFAutoModelForMaskedImageModeling
+
+### AutoModelForObjectDetection
+
+[[autodoc]] AutoModelForObjectDetection
+
+### AutoModelForImageSegmentation
+
+[[autodoc]] AutoModelForImageSegmentation
+
+### AutoModelForImageToImage
+
+[[autodoc]] AutoModelForImageToImage
+
+### AutoModelForSemanticSegmentation
+
+[[autodoc]] AutoModelForSemanticSegmentation
+
+### TFAutoModelForSemanticSegmentation
+
+[[autodoc]] TFAutoModelForSemanticSegmentation
+
+### AutoModelForInstanceSegmentation
+
+[[autodoc]] AutoModelForInstanceSegmentation
+
+### AutoModelForUniversalSegmentation
+
+[[autodoc]] AutoModelForUniversalSegmentation
+
+### AutoModelForZeroShotImageClassification
+
+[[autodoc]] AutoModelForZeroShotImageClassification
+
+### TFAutoModelForZeroShotImageClassification
+
+[[autodoc]] TFAutoModelForZeroShotImageClassification
+
+### AutoModelForZeroShotObjectDetection
+
+[[autodoc]] AutoModelForZeroShotObjectDetection
+
+## Audio
+
+以下の自動クラスは、次の音声タスクに利用可能です。
+
+### AutoModelForAudioClassification
+
+[[autodoc]] AutoModelForAudioClassification
+
+### AutoModelForAudioFrameClassification
+
+[[autodoc]] TFAutoModelForAudioClassification
+
+### TFAutoModelForAudioFrameClassification
+
+[[autodoc]] AutoModelForAudioFrameClassification
+
+### AutoModelForCTC
+
+[[autodoc]] AutoModelForCTC
+
+### AutoModelForSpeechSeq2Seq
+
+[[autodoc]] AutoModelForSpeechSeq2Seq
+
+### TFAutoModelForSpeechSeq2Seq
+
+[[autodoc]] TFAutoModelForSpeechSeq2Seq
+
+### FlaxAutoModelForSpeechSeq2Seq
+
+[[autodoc]] FlaxAutoModelForSpeechSeq2Seq
+
+### AutoModelForAudioXVector
+
+[[autodoc]] AutoModelForAudioXVector
+
+### AutoModelForTextToSpectrogram
+
+[[autodoc]] AutoModelForTextToSpectrogram
+
+### AutoModelForTextToWaveform
+
+[[autodoc]] AutoModelForTextToWaveform
+
+## Multimodal
+
+以下の自動クラスは、次のマルチモーダルタスクに利用可能です。
+
+### AutoModelForTableQuestionAnswering
+
+[[autodoc]] AutoModelForTableQuestionAnswering
+
+### TFAutoModelForTableQuestionAnswering
+
+[[autodoc]] TFAutoModelForTableQuestionAnswering
+
+### AutoModelForDocumentQuestionAnswering
+
+[[autodoc]] AutoModelForDocumentQuestionAnswering
+
+### TFAutoModelForDocumentQuestionAnswering
+
+[[autodoc]] TFAutoModelForDocumentQuestionAnswering
+
+### AutoModelForVisualQuestionAnswering
+
+[[autodoc]] AutoModelForVisualQuestionAnswering
+
+### AutoModelForVision2Seq
+
+[[autodoc]] AutoModelForVision2Seq
+
+### TFAutoModelForVision2Seq
+
+[[autodoc]] TFAutoModelForVision2Seq
+
+### FlaxAutoModelForVision2Seq
+
+[[autodoc]] FlaxAutoModelForVision2Seq
+
+### AutoModelForImageTextToText
+
+[[autodoc]] AutoModelForImageTextToText
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/autoformer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/autoformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..b8b0948b960d6920a31f5150264ca1e1ee9c0c9f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/autoformer.md
@@ -0,0 +1,50 @@
+
+
+# Autoformer
+
+## 概要
+
+Autoformerモデルは、「[Autoformer: Decomposition Transformers with Auto-Correlation for Long-Term Series Forecasting](https://arxiv.org/abs/2106.13008)」という論文でHaixu Wu、Jiehui Xu、Jianmin Wang、Mingsheng Longによって提案されました。
+
+このモデルは、予測プロセス中にトレンドと季節性成分を逐次的に分解できる深層分解アーキテクチャとしてTransformerを増強します。
+
+論文の要旨は以下の通りです:
+
+*例えば異常気象の早期警告や長期的なエネルギー消費計画といった実応用において、予測時間を延長することは重要な要求です。本論文では、時系列の長期予測問題を研究しています。以前のTransformerベースのモデルは、長距離依存関係を発見するために様々なセルフアテンション機構を採用しています。しかし、長期未来の複雑な時間的パターンによってモデルが信頼できる依存関係を見つけることを妨げられます。また、Transformerは、長い系列の効率化のためにポイントワイズなセルフアテンションのスパースバージョンを採用する必要があり、情報利用のボトルネックとなります。Transformerを超えて、我々は自己相関機構を持つ新しい分解アーキテクチャとしてAutoformerを設計しました。系列分解の事前処理の慣行を破り、それを深層モデルの基本的な内部ブロックとして革新します。この設計は、複雑な時系列に対するAutoformerの進行的な分解能力を強化します。さらに、確率過程理論に触発されて、系列の周期性に基づいた自己相関機構を設計し、サブ系列レベルでの依存関係の発見と表現の集約を行います。自己相関は効率と精度の両方でセルフアテンションを上回ります。長期予測において、Autoformerは、エネルギー、交通、経済、気象、疾病の5つの実用的な応用をカバーする6つのベンチマークで38%の相対的な改善をもたらし、最先端の精度を達成します。*
+
+このモデルは[elisim](https://huggingface.co/elisim)と[kashif](https://huggingface.co/kashif)より提供されました。
+オリジナルのコードは[こちら](https://github.com/thuml/Autoformer)で見ることができます。
+
+## 参考資料
+
+Autoformerの使用を開始するのに役立つ公式のHugging Faceおよびコミュニティ(🌎で示されている)の参考資料の一覧です。ここに参考資料を提出したい場合は、気兼ねなくPull Requestを開いてください。私たちはそれをレビューいたします!参考資料は、既存のものを複製するのではなく、何か新しいことを示すことが理想的です。
+
+- HuggingFaceブログでAutoformerに関するブログ記事をチェックしてください:[はい、Transformersは時系列予測に効果的です(+ Autoformer)](https://huggingface.co/blog/autoformer)
+
+## AutoformerConfig
+
+[[autodoc]] AutoformerConfig
+
+## AutoformerModel
+
+[[autodoc]] AutoformerModel
+ - forward
+
+## AutoformerForPrediction
+
+[[autodoc]] AutoformerForPrediction
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bark.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bark.md
new file mode 100644
index 0000000000000000000000000000000000000000..508b8938889bae6960bcd2dddd155a88052174cf
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bark.md
@@ -0,0 +1,198 @@
+
+
+# Bark
+
+## Overview
+
+Bark は、[suno-ai/bark](https://github.com/suno-ai/bark) で Suno AI によって提案されたトランスフォーマーベースのテキスト読み上げモデルです。
+
+
+Bark は 4 つの主要なモデルで構成されています。
+
+- [`BarkSemanticModel`] ('テキスト'モデルとも呼ばれる): トークン化されたテキストを入力として受け取り、テキストの意味を捉えるセマンティック テキスト トークンを予測する因果的自己回帰変換モデル。
+- [`BarkCoarseModel`] ('粗い音響' モデルとも呼ばれる): [`BarkSemanticModel`] モデルの結果を入力として受け取る因果的自己回帰変換器。 EnCodec に必要な最初の 2 つのオーディオ コードブックを予測することを目的としています。
+- [`BarkFineModel`] ('微細音響' モデル)、今回は非因果的オートエンコーダー トランスフォーマーで、以前のコードブック埋め込みの合計に基づいて最後のコードブックを繰り返し予測します。
+- [`EncodecModel`] からすべてのコードブック チャネルを予測したので、Bark はそれを使用して出力オーディオ配列をデコードします。
+
+最初の 3 つのモジュールはそれぞれ、特定の事前定義された音声に従って出力サウンドを調整するための条件付きスピーカー埋め込みをサポートできることに注意してください。
+
+### Optimizing Bark
+
+Bark は、コードを数行追加するだけで最適化でき、**メモリ フットプリントが大幅に削減**され、**推論が高速化**されます。
+
+#### Using half-precision
+
+モデルを半精度でロードするだけで、推論を高速化し、メモリ使用量を 50% 削減できます。
+
+```python
+from transformers import BarkModel
+import torch
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+model = BarkModel.from_pretrained("suno/bark-small", torch_dtype=torch.float16).to(device)
+```
+
+#### Using 🤗 Better Transformer
+
+Better Transformer は、内部でカーネル融合を実行する 🤗 最適な機能です。パフォーマンスを低下させることなく、速度を 20% ~ 30% 向上させることができます。モデルを 🤗 Better Transformer にエクスポートするのに必要なコードは 1 行だけです。
+
+```python
+model = model.to_bettertransformer()
+```
+
+この機能を使用する前に 🤗 Optimum をインストールする必要があることに注意してください。 [インストール方法はこちら](https://huggingface.co/docs/optimum/installation)
+
+#### Using CPU offload
+
+前述したように、Bark は 4 つのサブモデルで構成されており、オーディオ生成中に順番に呼び出されます。言い換えれば、1 つのサブモデルが使用されている間、他のサブモデルはアイドル状態になります。
+
+CUDA デバイスを使用している場合、メモリ フットプリントの 80% 削減による恩恵を受ける簡単な解決策は、アイドル状態の GPU のサブモデルをオフロードすることです。この操作は CPU オフロードと呼ばれます。 1行のコードで使用できます。
+
+```python
+model.enable_cpu_offload()
+```
+
+この機能を使用する前に、🤗 Accelerate をインストールする必要があることに注意してください。 [インストール方法はこちら](https://huggingface.co/docs/accelerate/basic_tutorials/install)
+
+#### Combining optimization techniques
+
+最適化手法を組み合わせて、CPU オフロード、半精度、🤗 Better Transformer をすべて一度に使用できます。
+
+```python
+from transformers import BarkModel
+import torch
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+
+# load in fp16
+model = BarkModel.from_pretrained("suno/bark-small", torch_dtype=torch.float16).to(device)
+
+# convert to bettertransformer
+model = BetterTransformer.transform(model, keep_original_model=False)
+
+# enable CPU offload
+model.enable_cpu_offload()
+```
+
+推論最適化手法の詳細については、[こちら](https://huggingface.co/docs/transformers/perf_infer_gpu_one) をご覧ください。
+
+### Tips
+
+Suno は、多くの言語で音声プリセットのライブラリを提供しています [こちら](https://suno-ai.notion.site/8b8e8749ed514b0cbf3f699013548683?v=bc67cff786b04b50b3ceb756fd05f68c)。
+これらのプリセットは、ハブ [こちら](https://huggingface.co/suno/bark-small/tree/main/speaker_embeddings) または [こちら](https://huggingface.co/suno/bark/tree/main/speaker_embeddings)。
+
+```python
+>>> from transformers import AutoProcessor, BarkModel
+
+>>> processor = AutoProcessor.from_pretrained("suno/bark")
+>>> model = BarkModel.from_pretrained("suno/bark")
+
+>>> voice_preset = "v2/en_speaker_6"
+
+>>> inputs = processor("Hello, my dog is cute", voice_preset=voice_preset)
+
+>>> audio_array = model.generate(**inputs)
+>>> audio_array = audio_array.cpu().numpy().squeeze()
+```
+
+Bark は、非常にリアルな **多言語** 音声だけでなく、音楽、背景ノイズ、単純な効果音などの他の音声も生成できます。
+
+```python
+>>> # Multilingual speech - simplified Chinese
+>>> inputs = processor("惊人的!我会说中文")
+
+>>> # Multilingual speech - French - let's use a voice_preset as well
+>>> inputs = processor("Incroyable! Je peux générer du son.", voice_preset="fr_speaker_5")
+
+>>> # Bark can also generate music. You can help it out by adding music notes around your lyrics.
+>>> inputs = processor("♪ Hello, my dog is cute ♪")
+
+>>> audio_array = model.generate(**inputs)
+>>> audio_array = audio_array.cpu().numpy().squeeze()
+```
+
+このモデルは、笑う、ため息、泣くなどの**非言語コミュニケーション**を生成することもできます。
+
+
+```python
+>>> # Adding non-speech cues to the input text
+>>> inputs = processor("Hello uh ... [clears throat], my dog is cute [laughter]")
+
+>>> audio_array = model.generate(**inputs)
+>>> audio_array = audio_array.cpu().numpy().squeeze()
+```
+
+オーディオを保存するには、モデル設定と scipy ユーティリティからサンプル レートを取得するだけです。
+
+```python
+>>> from scipy.io.wavfile import write as write_wav
+
+>>> # save audio to disk, but first take the sample rate from the model config
+>>> sample_rate = model.generation_config.sample_rate
+>>> write_wav("bark_generation.wav", sample_rate, audio_array)
+```
+
+このモデルは、[Yoach Lacombe (ylacombe)](https://huggingface.co/ylacombe) および [Sanchit Gandhi (sanchit-gandhi)](https://github.com/sanchit-gandhi) によって提供されました。
+元のコードは [ここ](https://github.com/suno-ai/bark) にあります。
+
+## BarkConfig
+
+[[autodoc]] BarkConfig
+ - all
+
+## BarkProcessor
+
+[[autodoc]] BarkProcessor
+ - all
+ - __call__
+
+## BarkModel
+
+[[autodoc]] BarkModel
+ - generate
+ - enable_cpu_offload
+
+## BarkSemanticModel
+
+[[autodoc]] BarkSemanticModel
+ - forward
+
+## BarkCoarseModel
+
+[[autodoc]] BarkCoarseModel
+ - forward
+
+## BarkFineModel
+
+[[autodoc]] BarkFineModel
+ - forward
+
+## BarkCausalModel
+
+[[autodoc]] BarkCausalModel
+ - forward
+
+## BarkCoarseConfig
+
+[[autodoc]] BarkCoarseConfig
+ - all
+
+## BarkFineConfig
+
+[[autodoc]] BarkFineConfig
+ - all
+
+## BarkSemanticConfig
+
+[[autodoc]] BarkSemanticConfig
+ - all
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bart.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bart.md
new file mode 100644
index 0000000000000000000000000000000000000000..5c71da37f01eb48049ab65c8ba33e5fdc49a415d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bart.md
@@ -0,0 +1,223 @@
+
+
+# BART
+
+
+
+**免責事項:** 何か奇妙なものを見つけた場合は、[Github 問題](https://github.com/huggingface/transformers/issues/new?assignees=&labels=&template=bug-report.md&title) を提出し、割り当ててください。
+@patrickvonplaten
+
+## Overview
+
+Bart モデルは、[BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation、
+翻訳と理解](https://arxiv.org/abs/1910.13461) Mike Lewis、Yinhan Liu、Naman Goyal、Marjan 著
+ガズビニネジャド、アブデルラフマン・モハメド、オメル・レヴィ、ベス・ストヤノフ、ルーク・ゼトルモイヤー、2019年10月29日。
+
+要約によると、
+
+- Bart は、双方向エンコーダ (BERT など) を備えた標準の seq2seq/機械翻訳アーキテクチャを使用します。
+ 左から右へのデコーダ (GPT など)。
+- 事前トレーニング タスクには、元の文の順序をランダムにシャッフルし、新しい埋め込みスキームが含まれます。
+ ここで、テキストの範囲は単一のマスク トークンに置き換えられます。
+- BART は、テキスト生成用に微調整した場合に特に効果的ですが、理解タスクにも適しています。それ
+ RoBERTa のパフォーマンスを GLUE および SQuAD の同等のトレーニング リソースと同等にし、新たな成果を達成します。
+ さまざまな抽象的な対話、質問応答、要約タスクに関する最先端の結果が得られ、成果が得られます。
+ ルージュは最大6枚まで。
+
+チップ:
+
+- BART は絶対位置埋め込みを備えたモデルであるため、通常は入力を右側にパディングすることをお勧めします。
+ 左。
+- エンコーダーとデコーダーを備えたシーケンスツーシーケンス モデル。エンコーダには破損したバージョンのトークンが供給され、デコーダには元のトークンが供給されます(ただし、通常のトランスフォーマー デコーダと同様に、将来のワードを隠すためのマスクがあります)。次の変換の構成は、エンコーダーの事前トレーニング タスクに適用されます。
+
+ * ランダムなトークンをマスクします (BERT と同様)
+ * ランダムなトークンを削除します
+ * k 個のトークンのスパンを 1 つのマスク トークンでマスクします (0 トークンのスパンはマスク トークンの挿入です)
+ * 文を並べ替えます
+ * ドキュメントを回転して特定のトークンから開始するようにします
+
+このモデルは [sshleifer](https://huggingface.co/sshleifer) によって提供されました。著者のコードは [ここ](https://github.com/pytorch/fairseq/tree/master/examples/bart) にあります。
+
+### Examples
+
+- シーケンス間タスク用の BART およびその他のモデルを微調整するための例とスクリプトは、次の場所にあります。
+ [examples/pytorch/summarization/](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization/README.md)。
+- Hugging Face `datasets` を使用して [`BartForConditionalGeneration`] をトレーニングする方法の例
+ オブジェクトは、この [フォーラム ディスカッション](https://discuss.huggingface.co/t/train-bart-for-conditional-generation-e-g-summarization/1904) で見つけることができます。
+- [抽出されたチェックポイント](https://huggingface.co/models?search=distilbart) は、この [論文](https://arxiv.org/abs/2010.13002) で説明されています。
+
+## Implementation Notes
+
+- Bart はシーケンスの分類に `token_type_ids` を使用しません。 [`BartTokenizer`] を使用するか、
+ [`~BartTokenizer.encode`] を使用して適切に分割します。
+- [`BartModel`] のフォワードパスは、渡されなかった場合、`decoder_input_ids` を作成します。
+ これは、他のモデリング API とは異なります。この機能の一般的な使用例は、マスクの塗りつぶしです。
+- モデルの予測は、次の場合に元の実装と同一になるように意図されています。
+ `forced_bos_token_id=0`。ただし、これは、渡す文字列が次の場合にのみ機能します。
+ [`fairseq.encode`] はスペースで始まります。
+- [`~generation.GenerationMixin.generate`] は、次のような条件付き生成タスクに使用する必要があります。
+ 要約については、その docstring の例を参照してください。
+- *facebook/bart-large-cnn* 重みをロードするモデルには `mask_token_id` がないか、実行できません。
+ マスクを埋めるタスク。
+
+## Mask Filling
+
+`facebook/bart-base` および `facebook/bart-large` チェックポイントを使用して、マルチトークン マスクを埋めることができます。
+
+```python
+from transformers import BartForConditionalGeneration, BartTokenizer
+
+model = BartForConditionalGeneration.from_pretrained("facebook/bart-large", forced_bos_token_id=0)
+tok = BartTokenizer.from_pretrained("facebook/bart-large")
+example_english_phrase = "UN Chief Says There Is No in Syria"
+batch = tok(example_english_phrase, return_tensors="pt")
+generated_ids = model.generate(batch["input_ids"])
+assert tok.batch_decode(generated_ids, skip_special_tokens=True) == [
+ "UN Chief Says There Is No Plan to Stop Chemical Weapons in Syria"
+]
+```
+
+## Resources
+
+BART を始めるのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示されている) リソースのリスト。ここに含めるリソースの送信に興味がある場合は、お気軽にプル リクエストを開いてください。審査させていただきます。リソースは、既存のリソースを複製するのではなく、何か新しいものを示すことが理想的です。
+
+
+
+BARThez の実装は、トークン化を除いて BART と同じです。詳細については、[BART ドキュメント](bart) を参照してください。
+構成クラスとそのパラメータ。 BARThez 固有のトークナイザーについては以下に記載されています。
+
+
+
+### Resources
+
+- BARThez は、BART と同様の方法でシーケンス間のタスクを微調整できます。以下を確認してください。
+ [examples/pytorch/summarization/](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization/README.md)。
+
+
+## BarthezTokenizer
+
+[[autodoc]] BarthezTokenizer
+
+## BarthezTokenizerFast
+
+[[autodoc]] BarthezTokenizerFast
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bartpho.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bartpho.md
new file mode 100644
index 0000000000000000000000000000000000000000..a9575d821ef916b55f4d06810cc4ab739a9c3504
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bartpho.md
@@ -0,0 +1,86 @@
+
+
+# BARTpho
+
+## Overview
+
+BARTpho モデルは、Nguyen Luong Tran、Duong Minh Le、Dat Quoc Nguyen によって [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnam](https://arxiv.org/abs/2109.09701) で提案されました。
+
+論文の要約は次のとおりです。
+
+*BARTpho には、BARTpho_word と BARTpho_syllable の 2 つのバージョンがあり、初の公開された大規模な単一言語です。
+ベトナム語用に事前トレーニングされたシーケンスツーシーケンス モデル。当社の BARTpho は「大規模な」アーキテクチャと事前トレーニングを使用します
+シーケンス間ノイズ除去モデル BART のスキームなので、生成 NLP タスクに特に適しています。実験
+ベトナム語テキスト要約の下流タスクでは、自動評価と人間による評価の両方で、BARTpho が
+強力なベースライン mBART を上回り、最先端の性能を向上させます。将来を容易にするためにBARTphoをリリースします
+生成的なベトナム語 NLP タスクの研究と応用。*
+
+このモデルは [dqnguyen](https://huggingface.co/dqnguyen) によって提供されました。元のコードは [こちら](https://github.com/VinAIResearch/BARTpho) にあります。
+
+## Usage example
+
+```python
+>>> import torch
+>>> from transformers import AutoModel, AutoTokenizer
+
+>>> bartpho = AutoModel.from_pretrained("vinai/bartpho-syllable")
+
+>>> tokenizer = AutoTokenizer.from_pretrained("vinai/bartpho-syllable")
+
+>>> line = "Chúng tôi là những nghiên cứu viên."
+
+>>> input_ids = tokenizer(line, return_tensors="pt")
+
+>>> with torch.no_grad():
+... features = bartpho(**input_ids) # Models outputs are now tuples
+
+>>> # With TensorFlow 2.0+:
+>>> from transformers import TFAutoModel
+
+>>> bartpho = TFAutoModel.from_pretrained("vinai/bartpho-syllable")
+>>> input_ids = tokenizer(line, return_tensors="tf")
+>>> features = bartpho(**input_ids)
+```
+
+## Usage tips
+
+- mBARTに続いて、BARTphoはBARTの「大規模な」アーキテクチャを使用し、その上に追加の層正規化層を備えています。
+ エンコーダとデコーダの両方。したがって、[BART のドキュメント](bart) の使用例は、使用に適応する場合に使用されます。
+ BARTpho を使用する場合は、BART に特化したクラスを mBART に特化した対応するクラスに置き換えることによって調整する必要があります。
+ 例えば:
+
+```python
+>>> from transformers import MBartForConditionalGeneration
+
+>>> bartpho = MBartForConditionalGeneration.from_pretrained("vinai/bartpho-syllable")
+>>> TXT = "Chúng tôi là nghiên cứu viên."
+>>> input_ids = tokenizer([TXT], return_tensors="pt")["input_ids"]
+>>> logits = bartpho(input_ids).logits
+>>> masked_index = (input_ids[0] == tokenizer.mask_token_id).nonzero().item()
+>>> probs = logits[0, masked_index].softmax(dim=0)
+>>> values, predictions = probs.topk(5)
+>>> print(tokenizer.decode(predictions).split())
+```
+
+- この実装はトークン化のみを目的としています。`monolingual_vocab_file`はベトナム語に特化した型で構成されています
+ 多言語 XLM-RoBERTa から利用できる事前トレーニング済み SentencePiece モデル`vocab_file`から抽出されます。
+ 他の言語 (サブワードにこの事前トレーニング済み多言語 SentencePiece モデル`vocab_file`を使用する場合)
+ セグメンテーションにより、独自の言語に特化した`monolingual_vocab_file`を使用して BartphoTokenizer を再利用できます。
+
+## BartphoTokenizer
+
+[[autodoc]] BartphoTokenizer
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/beit.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/beit.md
new file mode 100644
index 0000000000000000000000000000000000000000..45eb1efa5dd873d2e770d6cd727cb08ea26ea70b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/beit.md
@@ -0,0 +1,143 @@
+
+
+# BEiT
+
+## Overview
+
+BEiT モデルは、[BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) で提案されました。
+ハンボ・バオ、リー・ドン、フル・ウェイ。 BERT に触発された BEiT は、自己教師ありの事前トレーニングを作成した最初の論文です。
+ビジョン トランスフォーマー (ViT) は、教師付き事前トレーニングよりも優れたパフォーマンスを発揮します。クラスを予測するためにモデルを事前トレーニングするのではなく
+([オリジナルの ViT 論文](https://arxiv.org/abs/2010.11929) で行われたように) 画像の BEiT モデルは、次のように事前トレーニングされています。
+マスクされた OpenAI の [DALL-E モデル](https://arxiv.org/abs/2102.12092) のコードブックからビジュアル トークンを予測します
+パッチ。
+
+論文の要約は次のとおりです。
+
+*自己教師あり視覚表現モデル BEiT (Bidirectional Encoderpresentation) を導入します。
+イメージトランスフォーマーより。自然言語処理分野で開発されたBERTに倣い、マスク画像を提案します。
+ビジョントランスフォーマーを事前にトレーニングするためのモデリングタスク。具体的には、事前トレーニングでは各画像に 2 つのビューがあります。
+パッチ (16x16 ピクセルなど)、およびビジュアル トークン (つまり、個別のトークン)。まず、元の画像を「トークン化」して、
+ビジュアルトークン。次に、いくつかの画像パッチをランダムにマスクし、それらをバックボーンの Transformer に供給します。事前トレーニング
+目的は、破損したイメージ パッチに基づいて元のビジュアル トークンを回復することです。 BEiTの事前トレーニング後、
+事前トレーニングされたエンコーダーにタスク レイヤーを追加することで、ダウンストリーム タスクのモデル パラメーターを直接微調整します。
+画像分類とセマンティックセグメンテーションに関する実験結果は、私たちのモデルが競争力のある結果を達成することを示しています
+以前の事前トレーニング方法を使用して。たとえば、基本サイズの BEiT は、ImageNet-1K で 83.2% のトップ 1 精度を達成します。
+同じ設定でゼロからの DeiT トレーニング (81.8%) を大幅に上回りました。また、大型BEiTは
+86.3% は ImageNet-1K のみを使用しており、ImageNet-22K での教師付き事前トレーニングを使用した ViT-L (85.2%) を上回っています。*
+
+## Usage tips
+
+- BEiT モデルは通常のビジョン トランスフォーマーですが、教師ありではなく自己教師ありの方法で事前トレーニングされています。彼らは
+ ImageNet-1K および CIFAR-100 で微調整すると、[オリジナル モデル (ViT)](vit) と [データ効率の高いイメージ トランスフォーマー (DeiT)](deit) の両方を上回るパフォーマンスを発揮します。推論に関するデモノートブックもチェックできます。
+ カスタム データの微調整は [こちら](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/VisionTransformer) (置き換えるだけで済みます)
+ [`BeitImageProcessor`] による [`ViTFeatureExtractor`] と
+ [`ViTForImageClassification`] by [`BeitForImageClassification`])。
+- DALL-E の画像トークナイザーと BEiT を組み合わせる方法を紹介するデモ ノートブックも利用可能です。
+ マスクされた画像モデリングを実行します。 [ここ](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/BEiT) で見つけることができます。
+- BEiT モデルは各画像が同じサイズ (解像度) であることを期待しているため、次のように使用できます。
+ [`BeitImageProcessor`] を使用して、モデルの画像のサイズを変更 (または再スケール) し、正規化します。
+- 事前トレーニングまたは微調整中に使用されるパッチ解像度と画像解像度の両方が名前に反映されます。
+ 各チェックポイント。たとえば、`microsoft/beit-base-patch16-224`は、パッチ付きの基本サイズのアーキテクチャを指します。
+ 解像度は 16x16、微調整解像度は 224x224 です。すべてのチェックポイントは [ハブ](https://huggingface.co/models?search=microsoft/beit) で見つけることができます。
+- 利用可能なチェックポイントは、(1) [ImageNet-22k](http://www.image-net.org/) で事前トレーニングされています (
+ 1,400 万の画像と 22,000 のクラス) のみ、(2) ImageNet-22k でも微調整、または (3) [ImageNet-1k](http://www.image-net.org/challenges/LSVRC)でも微調整/2012/) (ILSVRC 2012 とも呼ばれ、130 万件のコレクション)
+ 画像と 1,000 クラス)。
+- BEiT は、T5 モデルからインスピレーションを得た相対位置埋め込みを使用します。事前トレーニング中に、著者は次のことを共有しました。
+ いくつかの自己注意層間の相対的な位置の偏り。微調整中、各レイヤーの相対位置
+ バイアスは、事前トレーニング後に取得された共有相対位置バイアスで初期化されます。ご希望の場合は、
+ モデルを最初から事前トレーニングするには、`use_relative_position_bias` または
+ 追加するには、[`BeitConfig`] の `use_relative_position_bias` 属性を `True` に設定します。
+ 位置の埋め込み。
+
+ BEiT の事前トレーニング。 元の論文から抜粋。
+
+このモデルは、[nielsr](https://huggingface.co/nielsr) によって提供されました。このモデルの JAX/FLAX バージョンは、
+[kamalkraj](https://huggingface.co/kamalkraj) による投稿。元のコードは [ここ](https://github.com/microsoft/unilm/tree/master/beit) にあります。
+
+## Resources
+
+BEiT の使用を開始するのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示されている) リソースのリスト。
+
+
+
+- この実装はトークン化方法を除いて BERT と同じです。その他の使用例については、[BERT のドキュメント](bert) を参照してください。
+
+
+
+このモデルは[cl-tohaku](https://huggingface.co/cl-tohaku)から提供されました。
+
+## BertJapaneseTokenizer
+
+[[autodoc]] BertJapaneseTokenizer
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bert.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bert.md
new file mode 100644
index 0000000000000000000000000000000000000000..d34df9c0d5d60e7069af756bf825ef1db7cf3f74
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bert.md
@@ -0,0 +1,312 @@
+
+
+# BERT
+
+
+
+## Overview
+
+BERT モデルは、Jacob Devlin、Ming-Wei Chang、Kenton Lee、Kristina Toutanova によって [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) で提案されました。それは
+マスクされた言語モデリング目標と次の文の組み合わせを使用して事前トレーニングされた双方向トランスフォーマー
+Toronto Book Corpus と Wikipedia からなる大規模なコーパスでの予測。
+
+論文の要約は次のとおりです。
+
+*BERT と呼ばれる新しい言語表現モデルを導入します。これは Bidirectional Encoder Representations の略です
+トランスフォーマーより。最近の言語表現モデルとは異なり、BERT は深い双方向性を事前にトレーニングするように設計されています。
+すべてのレイヤーの左と右の両方のコンテキストを共同で条件付けすることにより、ラベルのないテキストから表現します。結果として、
+事前トレーニングされた BERT モデルは、出力層を 1 つ追加するだけで微調整して、最先端のモデルを作成できます。
+実質的なタスク固有のものを必要とせず、質問応答や言語推論などの幅広いタスクに対応
+アーキテクチャの変更。*
+
+*BERT は概念的にはシンプルですが、経験的に強力です。 11 の自然な要素に関する新しい最先端の結果が得られます。
+言語処理タスク(GLUE スコアを 80.5% に押し上げる(7.7% ポイントの絶対改善)、MultiNLI を含む)
+精度は 86.7% (絶対値 4.6% 向上)、SQuAD v1.1 質問応答テスト F1 は 93.2 (絶対値 1.5 ポイント)
+改善) および SQuAD v2.0 テスト F1 から 83.1 (5.1 ポイントの絶対改善)。*
+
+## Usage tips
+
+- BERT は絶対位置埋め込みを備えたモデルであるため、通常は入力を右側にパディングすることをお勧めします。
+ 左。
+- BERT は、マスク言語モデリング (MLM) および次の文予測 (NSP) の目標を使用してトレーニングされました。それは
+ マスクされたトークンの予測や NLU では一般に効率的ですが、テキスト生成には最適ではありません。
+- ランダム マスキングを使用して入力を破壊します。より正確には、事前トレーニング中に、トークンの指定された割合 (通常は 15%) が次によってマスクされます。
+
+ * 確率0.8の特別なマスクトークン
+ * 確率 0.1 でマスクされたトークンとは異なるランダムなトークン
+ * 確率 0.1 の同じトークン
+
+- モデルは元の文を予測する必要がありますが、2 番目の目的があります。入力は 2 つの文 A と B (間に分離トークンあり) です。確率 50% では、文はコーパス内で連続していますが、残りの 50% では関連性がありません。モデルは、文が連続しているかどうかを予測する必要があります。
+
+
+
+このモデルは [thomwolf](https://huggingface.co/thomwolf) によって提供されました。元のコードは [こちら](https://github.com/google-research/bert) にあります。
+
+## Resources
+
+BERT を始めるのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示される) リソースのリスト。ここに含めるリソースの送信に興味がある場合は、お気軽にプル リクエストを開いてください。審査させていただきます。リソースは、既存のリソースを複製するのではなく、何か新しいものを示すことが理想的です。
+
+
+
+
+## BertTokenizerFast
+
+[[autodoc]] BertTokenizerFast
+
+
+
+
+## TFBertTokenizer
+
+[[autodoc]] TFBertTokenizer
+
+
+
+
+## Bert specific outputs
+
+[[autodoc]] models.bert.modeling_bert.BertForPreTrainingOutput
+
+[[autodoc]] models.bert.modeling_tf_bert.TFBertForPreTrainingOutput
+
+[[autodoc]] models.bert.modeling_flax_bert.FlaxBertForPreTrainingOutput
+
+
+
+
+## BertModel
+
+[[autodoc]] BertModel
+ - forward
+
+## BertForPreTraining
+
+[[autodoc]] BertForPreTraining
+ - forward
+
+## BertLMHeadModel
+
+[[autodoc]] BertLMHeadModel
+ - forward
+
+## BertForMaskedLM
+
+[[autodoc]] BertForMaskedLM
+ - forward
+
+## BertForNextSentencePrediction
+
+[[autodoc]] BertForNextSentencePrediction
+ - forward
+
+## BertForSequenceClassification
+
+[[autodoc]] BertForSequenceClassification
+ - forward
+
+## BertForMultipleChoice
+
+[[autodoc]] BertForMultipleChoice
+ - forward
+
+## BertForTokenClassification
+
+[[autodoc]] BertForTokenClassification
+ - forward
+
+## BertForQuestionAnswering
+
+[[autodoc]] BertForQuestionAnswering
+ - forward
+
+
+
+
+## TFBertModel
+
+[[autodoc]] TFBertModel
+ - call
+
+## TFBertForPreTraining
+
+[[autodoc]] TFBertForPreTraining
+ - call
+
+## TFBertModelLMHeadModel
+
+[[autodoc]] TFBertLMHeadModel
+ - call
+
+## TFBertForMaskedLM
+
+[[autodoc]] TFBertForMaskedLM
+ - call
+
+## TFBertForNextSentencePrediction
+
+[[autodoc]] TFBertForNextSentencePrediction
+ - call
+
+## TFBertForSequenceClassification
+
+[[autodoc]] TFBertForSequenceClassification
+ - call
+
+## TFBertForMultipleChoice
+
+[[autodoc]] TFBertForMultipleChoice
+ - call
+
+## TFBertForTokenClassification
+
+[[autodoc]] TFBertForTokenClassification
+ - call
+
+## TFBertForQuestionAnswering
+
+[[autodoc]] TFBertForQuestionAnswering
+ - call
+
+
+
+
+
+## FlaxBertModel
+
+[[autodoc]] FlaxBertModel
+ - __call__
+
+## FlaxBertForPreTraining
+
+[[autodoc]] FlaxBertForPreTraining
+ - __call__
+
+## FlaxBertForCausalLM
+
+[[autodoc]] FlaxBertForCausalLM
+ - __call__
+
+## FlaxBertForMaskedLM
+
+[[autodoc]] FlaxBertForMaskedLM
+ - __call__
+
+## FlaxBertForNextSentencePrediction
+
+[[autodoc]] FlaxBertForNextSentencePrediction
+ - __call__
+
+## FlaxBertForSequenceClassification
+
+[[autodoc]] FlaxBertForSequenceClassification
+ - __call__
+
+## FlaxBertForMultipleChoice
+
+[[autodoc]] FlaxBertForMultipleChoice
+ - __call__
+
+## FlaxBertForTokenClassification
+
+[[autodoc]] FlaxBertForTokenClassification
+ - __call__
+
+## FlaxBertForQuestionAnswering
+
+[[autodoc]] FlaxBertForQuestionAnswering
+ - __call__
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bertweet.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bertweet.md
new file mode 100644
index 0000000000000000000000000000000000000000..3a5dddbf04cc5884576083fbddac127ff24ec8ae
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bertweet.md
@@ -0,0 +1,68 @@
+
+
+# BERTweet
+
+## Overview
+
+BERTweet モデルは、Dat Quoc Nguyen、Thanh Vu によって [BERTweet: A pre-trained language model for English Tweets](https://www.aclweb.org/anthology/2020.emnlp-demos.2.pdf) で提案されました。アン・トゥアン・グエンさん。
+
+論文の要約は次のとおりです。
+
+*私たちは、英語ツイート用に初めて公開された大規模な事前トレーニング済み言語モデルである BERTweet を紹介します。私たちのBERTweetは、
+BERT ベースと同じアーキテクチャ (Devlin et al., 2019) は、RoBERTa 事前トレーニング手順 (Liu et al.) を使用してトレーニングされます。
+al.、2019)。実験では、BERTweet が強力なベースラインである RoBERTa ベースおよび XLM-R ベースを上回るパフォーマンスを示すことが示されています (Conneau et al.,
+2020)、3 つのツイート NLP タスクにおいて、以前の最先端モデルよりも優れたパフォーマンス結果が得られました。
+品詞タグ付け、固有表現認識およびテキスト分類。*
+
+## Usage example
+
+```python
+>>> import torch
+>>> from transformers import AutoModel, AutoTokenizer
+
+>>> bertweet = AutoModel.from_pretrained("vinai/bertweet-base")
+
+>>> # For transformers v4.x+:
+>>> tokenizer = AutoTokenizer.from_pretrained("vinai/bertweet-base", use_fast=False)
+
+>>> # For transformers v3.x:
+>>> # tokenizer = AutoTokenizer.from_pretrained("vinai/bertweet-base")
+
+>>> # INPUT TWEET IS ALREADY NORMALIZED!
+>>> line = "SC has first two presumptive cases of coronavirus , DHEC confirms HTTPURL via @USER :cry:"
+
+>>> input_ids = torch.tensor([tokenizer.encode(line)])
+
+>>> with torch.no_grad():
+... features = bertweet(input_ids) # Models outputs are now tuples
+
+>>> # With TensorFlow 2.0+:
+>>> # from transformers import TFAutoModel
+>>> # bertweet = TFAutoModel.from_pretrained("vinai/bertweet-base")
+```
+
+
+この実装は、トークン化方法を除いて BERT と同じです。詳細については、[BERT ドキュメント](bert) を参照してください。
+API リファレンス情報。
+
+
+
+このモデルは [dqnguyen](https://huggingface.co/dqnguyen) によって提供されました。元のコードは [ここ](https://github.com/VinAIResearch/BERTweet) にあります。
+
+## BertweetTokenizer
+
+[[autodoc]] BertweetTokenizer
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/big_bird.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/big_bird.md
new file mode 100644
index 0000000000000000000000000000000000000000..4c0dabbebb46d4b9eb8bb25a8ada0d80076e5c85
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/big_bird.md
@@ -0,0 +1,176 @@
+
+
+# BigBird
+
+## Overview
+
+BigBird モデルは、[Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) で提案されました。
+ザヒール、マンジルとグルガネシュ、グルとダベイ、クマール・アヴィナヴァとエインズリー、ジョシュアとアルベルティ、クリスとオンタノン、
+サンティアゴとファム、フィリップとラブラ、アニルードとワン、キーファンとヤン、リーなど。 BigBird は注目度が低い
+BERT などの Transformer ベースのモデルをさらに長いシーケンスに拡張する、Transformer ベースのモデル。まばらに加えて
+アテンションと同様に、BigBird は入力シーケンスにランダム アテンションだけでなくグローバル アテンションも適用します。理論的には、
+まばらで全体的でランダムな注意を適用すると、完全な注意に近づくことが示されていますが、
+長いシーケンスでは計算効率が大幅に向上します。より長いコンテキストを処理できる機能の結果として、
+BigBird は、質問応答や
+BERT または RoBERTa と比較した要約。
+
+論文の要約は次のとおりです。
+
+*BERT などのトランスフォーマーベースのモデルは、NLP で最も成功した深層学習モデルの 1 つです。
+残念ながら、それらの中核的な制限の 1 つは、シーケンスに対する二次依存性 (主にメモリに関する) です。
+完全な注意メカニズムによる長さです。これを解決するために、BigBird は、まばらな注意メカニズムを提案します。
+この二次依存関係を線形に削減します。 BigBird がシーケンス関数の汎用近似器であることを示します。
+チューリングは完全であるため、二次完全注意モデルのこれらの特性が保存されます。途中、私たちの
+理論分析により、O(1) 個のグローバル トークン (CLS など) を持つ利点の一部が明らかになり、
+スパース注意メカニズムの一部としてのシーケンス。提案されたスパース アテンションは、次の長さのシーケンスを処理できます。
+同様のハードウェアを使用して以前に可能であったものの 8 倍。より長いコンテキストを処理できる機能の結果として、
+BigBird は、質問応答や要約などのさまざまな NLP タスクのパフォーマンスを大幅に向上させます。私達も
+ゲノミクスデータへの新しいアプリケーションを提案します。*
+
+チップ:
+
+- BigBird の注意がどのように機能するかについての詳細な説明については、[このブログ投稿](https://huggingface.co/blog/big-bird) を参照してください。
+- BigBird には、**original_full** と **block_sparse** の 2 つの実装が付属しています。シーケンス長が 1024 未満の場合、次を使用します。
+ **block_sparse** を使用してもメリットがないため、**original_full** を使用することをお勧めします。
+- コードは現在、3 ブロックと 2 グローバル ブロックのウィンドウ サイズを使用しています。
+- シーケンスの長さはブロック サイズで割り切れる必要があります。
+- 現在の実装では **ITC** のみがサポートされています。
+- 現在の実装では **num_random_blocks = 0** はサポートされていません
+- BigBird は絶対位置埋め込みを備えたモデルであるため、通常は入力を右側にパディングすることをお勧めします。
+ 左。
+
+ このモデルは、[vasudevgupta](https://huggingface.co/vasudevgupta) によって提供されました。元のコードが見つかる
+[こちら](https://github.com/google-research/bigbird)。
+
+## ドキュメント リソース
+
+- [テキスト分類タスクガイド](../tasks/sequence_classification)
+- [トークン分類タスクガイド](../tasks/token_classification)
+- [質問回答タスク ガイド](../tasks/question_answering)
+- [因果言語モデリング タスク ガイド](../tasks/language_modeling)
+- [マスクされた言語モデリング タスク ガイド](../tasks/masked_lang_modeling)
+- [多肢選択タスク ガイド](../tasks/multiple_choice)
+
+## BigBirdConfig
+
+[[autodoc]] BigBirdConfig
+
+## BigBirdTokenizer
+
+[[autodoc]] BigBirdTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## BigBirdTokenizerFast
+
+[[autodoc]] BigBirdTokenizerFast
+
+## BigBird specific outputs
+
+[[autodoc]] models.big_bird.modeling_big_bird.BigBirdForPreTrainingOutput
+
+
+
+
+## BigBirdModel
+
+[[autodoc]] BigBirdModel
+ - forward
+
+## BigBirdForPreTraining
+
+[[autodoc]] BigBirdForPreTraining
+ - forward
+
+## BigBirdForCausalLM
+
+[[autodoc]] BigBirdForCausalLM
+ - forward
+
+## BigBirdForMaskedLM
+
+[[autodoc]] BigBirdForMaskedLM
+ - forward
+
+## BigBirdForSequenceClassification
+
+[[autodoc]] BigBirdForSequenceClassification
+ - forward
+
+## BigBirdForMultipleChoice
+
+[[autodoc]] BigBirdForMultipleChoice
+ - forward
+
+## BigBirdForTokenClassification
+
+[[autodoc]] BigBirdForTokenClassification
+ - forward
+
+## BigBirdForQuestionAnswering
+
+[[autodoc]] BigBirdForQuestionAnswering
+ - forward
+
+
+
+
+## FlaxBigBirdModel
+
+[[autodoc]] FlaxBigBirdModel
+ - __call__
+
+## FlaxBigBirdForPreTraining
+
+[[autodoc]] FlaxBigBirdForPreTraining
+ - __call__
+
+## FlaxBigBirdForCausalLM
+
+[[autodoc]] FlaxBigBirdForCausalLM
+ - __call__
+
+## FlaxBigBirdForMaskedLM
+
+[[autodoc]] FlaxBigBirdForMaskedLM
+ - __call__
+
+## FlaxBigBirdForSequenceClassification
+
+[[autodoc]] FlaxBigBirdForSequenceClassification
+ - __call__
+
+## FlaxBigBirdForMultipleChoice
+
+[[autodoc]] FlaxBigBirdForMultipleChoice
+ - __call__
+
+## FlaxBigBirdForTokenClassification
+
+[[autodoc]] FlaxBigBirdForTokenClassification
+ - __call__
+
+## FlaxBigBirdForQuestionAnswering
+
+[[autodoc]] FlaxBigBirdForQuestionAnswering
+ - __call__
+
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bigbird_pegasus.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bigbird_pegasus.md
new file mode 100644
index 0000000000000000000000000000000000000000..e0132b4b5f86b53b5de6d669b35a9a41ae23e3b5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bigbird_pegasus.md
@@ -0,0 +1,95 @@
+
+
+# BigBirdPegasus
+
+## Overview
+
+BigBird モデルは、[Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) で提案されました。
+ザヒール、マンジルとグルガネシュ、グルとダベイ、クマール・アヴィナヴァとエインズリー、ジョシュアとアルベルティ、クリスとオンタノン、
+サンティアゴとファム、フィリップとラブラ、アニルードとワン、キーファンとヤン、リーなど。 BigBird は注目度が低い
+BERT などの Transformer ベースのモデルをさらに長いシーケンスに拡張する、Transformer ベースのモデル。まばらに加えて
+アテンションと同様に、BigBird は入力シーケンスにランダム アテンションだけでなくグローバル アテンションも適用します。理論的には、
+まばらで全体的でランダムな注意を適用すると、完全な注意に近づくことが示されていますが、
+長いシーケンスでは計算効率が大幅に向上します。より長いコンテキストを処理できる機能の結果として、
+BigBird は、質問応答や
+BERT または RoBERTa と比較した要約。
+
+論文の要約は次のとおりです。
+
+*BERT などのトランスフォーマーベースのモデルは、NLP で最も成功した深層学習モデルの 1 つです。
+残念ながら、それらの中核的な制限の 1 つは、シーケンスに対する二次依存性 (主にメモリに関する) です。
+完全な注意メカニズムによる長さです。これを解決するために、BigBird は、まばらな注意メカニズムを提案します。
+この二次依存関係を線形に削減します。 BigBird がシーケンス関数の汎用近似器であることを示します。
+チューリングは完全であるため、二次完全注意モデルのこれらの特性が保存されます。途中、私たちの
+理論分析により、O(1) 個のグローバル トークン (CLS など) を持つ利点の一部が明らかになり、
+スパース注意メカニズムの一部としてのシーケンス。提案されたスパース アテンションは、次の長さのシーケンスを処理できます。
+同様のハードウェアを使用して以前に可能であったものの 8 倍。より長いコンテキストを処理できる機能の結果として、
+BigBird は、質問応答や要約などのさまざまな NLP タスクのパフォーマンスを大幅に向上させます。私達も
+ゲノミクスデータへの新しいアプリケーションを提案します。*
+
+## Usage tips
+
+- BigBird の注意がどのように機能するかについての詳細な説明については、[このブログ投稿](https://huggingface.co/blog/big-bird) を参照してください。
+- BigBird には、**original_full** と **block_sparse** の 2 つの実装が付属しています。シーケンス長が 1024 未満の場合、次を使用します。
+ **block_sparse** を使用してもメリットがないため、**original_full** を使用することをお勧めします。
+- コードは現在、3 ブロックと 2 グローバル ブロックのウィンドウ サイズを使用しています。
+- シーケンスの長さはブロック サイズで割り切れる必要があります。
+- 現在の実装では **ITC** のみがサポートされています。
+- 現在の実装では **num_random_blocks = 0** はサポートされていません。
+- BigBirdPegasus は [PegasusTokenizer](https://github.com/huggingface/transformers/blob/main/src/transformers/models/pegasus/tokenization_pegasus.py) を使用します。
+- BigBird は絶対位置埋め込みを備えたモデルであるため、通常は入力を右側にパディングすることをお勧めします。
+ 左。
+
+元のコードは [こちら](https://github.com/google-research/bigbird) にあります。
+
+## ドキュメント リソース
+
+- [テキスト分類タスクガイド](../tasks/sequence_classification)
+- [質問回答タスク ガイド](../tasks/question_answering)
+- [因果言語モデリング タスク ガイド](../tasks/language_modeling)
+- [翻訳タスクガイド](../tasks/translation)
+- [要約タスクガイド](../tasks/summarization)
+
+## BigBirdPegasusConfig
+
+[[autodoc]] BigBirdPegasusConfig
+ - all
+
+## BigBirdPegasusModel
+
+[[autodoc]] BigBirdPegasusModel
+ - forward
+
+## BigBirdPegasusForConditionalGeneration
+
+[[autodoc]] BigBirdPegasusForConditionalGeneration
+ - forward
+
+## BigBirdPegasusForSequenceClassification
+
+[[autodoc]] BigBirdPegasusForSequenceClassification
+ - forward
+
+## BigBirdPegasusForQuestionAnswering
+
+[[autodoc]] BigBirdPegasusForQuestionAnswering
+ - forward
+
+## BigBirdPegasusForCausalLM
+
+[[autodoc]] BigBirdPegasusForCausalLM
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/biogpt.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/biogpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..0634062a6b7214f0bc7631826c05db31b1322bcd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/biogpt.md
@@ -0,0 +1,73 @@
+
+
+# BioGPT
+
+## Overview
+
+BioGPT モデルは、[BioGPT: generative pre-trained transformer for biomedical text generation and mining](https://academic.oup.com/bib/advance-article/doi/10.1093/bib/bbac409/6713511?guestAccessKey=a66d9b5d-4f83-4017-bb52-405815c907b9) by Renqian Luo、Liai Sun、Yingce Xia、 Tao Qin、Sheng Zhang、Hoifung Poon、Tie-Yan Liu。 BioGPT は、生物医学テキストの生成とマイニングのための、ドメイン固有の生成事前トレーニング済み Transformer 言語モデルです。 BioGPT は、Transformer 言語モデルのバックボーンに従い、1,500 万の PubMed 抄録で最初から事前トレーニングされています。
+
+論文の要約は次のとおりです。
+
+*事前トレーニング済み言語モデルは、一般的な自然言語領域での大きな成功に触発されて、生物医学領域でますます注目を集めています。一般言語ドメインの事前トレーニング済み言語モデルの 2 つの主なブランチ、つまり BERT (およびそのバリアント) と GPT (およびそのバリアント) のうち、1 つ目は BioBERT や PubMedBERT などの生物医学ドメインで広く研究されています。これらはさまざまな下流の生物医学的タスクで大きな成功を収めていますが、生成能力の欠如により応用範囲が制限されています。この論文では、大規模な生物医学文献で事前トレーニングされたドメイン固有の生成 Transformer 言語モデルである BioGPT を提案します。私たちは 6 つの生物医学的自然言語処理タスクで BioGPT を評価し、ほとんどのタスクで私たちのモデルが以前のモデルよりも優れていることを実証しました。特に、BC5CDR、KD-DTI、DDI のエンドツーエンド関係抽出タスクではそれぞれ 44.98%、38.42%、40.76% の F1 スコアを獲得し、PubMedQA では 78.2% の精度を獲得し、新記録を樹立しました。テキスト生成に関する私たちのケーススタディは、生物医学文献における BioGPT の利点をさらに実証し、生物医学用語の流暢な説明を生成します。*
+
+## Usage tips
+
+- BioGPT は絶対位置埋め込みを備えたモデルであるため、通常は入力を左側ではなく右側にパディングすることをお勧めします。
+- BioGPT は因果言語モデリング (CLM) 目的でトレーニングされているため、シーケンス内の次のトークンを予測するのに強力です。 run_generation.py サンプル スクリプトで確認できるように、この機能を利用すると、BioGPT は構文的に一貫したテキストを生成できます。
+- モデルは、以前に計算されたキーと値のアテンション ペアである`past_key_values`(PyTorch の場合) を入力として受け取ることができます。この (past_key_values または past) 値を使用すると、モデルがテキスト生成のコンテキストで事前に計算された値を再計算できなくなります。 PyTorch の使用法の詳細については、BioGptForCausalLM.forward() メソッドの past_key_values 引数を参照してください。
+
+このモデルは、[kamalkraj](https://huggingface.co/kamalkraj) によって提供されました。元のコードは [ここ](https://github.com/microsoft/BioGPT) にあります。
+
+## Documentation resources
+
+- [因果言語モデリング タスク ガイド](../tasks/language_modeling)
+
+## BioGptConfig
+
+[[autodoc]] BioGptConfig
+
+
+## BioGptTokenizer
+
+[[autodoc]] BioGptTokenizer
+ - save_vocabulary
+
+
+## BioGptModel
+
+[[autodoc]] BioGptModel
+ - forward
+
+
+## BioGptForCausalLM
+
+[[autodoc]] BioGptForCausalLM
+ - forward
+
+
+## BioGptForTokenClassification
+
+[[autodoc]] BioGptForTokenClassification
+ - forward
+
+
+## BioGptForSequenceClassification
+
+[[autodoc]] BioGptForSequenceClassification
+ - forward
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bit.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bit.md
new file mode 100644
index 0000000000000000000000000000000000000000..76b24fa64470a2180226f0eec5e96308c3e46559
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bit.md
@@ -0,0 +1,65 @@
+
+
+# Big Transfer (BiT)
+
+## Overview
+
+BiT モデルは、Alexander Kolesnikov、Lucas Beyer、Xiaohua Zhai、Joan Puigcerver、Jessica Yung、Sylvain Gelly によって [Big Transfer (BiT): General Visual Representation Learning](https://arxiv.org/abs/1912.11370) で提案されました。ニール・ホールズビー。
+BiT は、[ResNet](resnet) のようなアーキテクチャ (具体的には ResNetv2) の事前トレーニングをスケールアップするための簡単なレシピです。この方法により、転移学習が大幅に改善されます。
+
+論文の要約は次のとおりです。
+
+*事前トレーニングされた表現の転送により、サンプル効率が向上し、視覚用のディープ ニューラル ネットワークをトレーニングする際のハイパーパラメーター調整が簡素化されます。大規模な教師ありデータセットでの事前トレーニングと、ターゲット タスクでのモデルの微調整のパラダイムを再検討します。私たちは事前トレーニングをスケールアップし、Big Transfer (BiT) と呼ぶシンプルなレシピを提案します。いくつかの慎重に選択されたコンポーネントを組み合わせ、シンプルなヒューリスティックを使用して転送することにより、20 を超えるデータセットで優れたパフォーマンスを実現します。 BiT は、クラスごとに 1 つのサンプルから合計 100 万のサンプルまで、驚くほど広範囲のデータ領域にわたって良好にパフォーマンスを発揮します。 BiT は、ILSVRC-2012 で 87.5%、CIFAR-10 で 99.4%、19 タスクの Visual Task Adaptation Benchmark (VTAB) で 76.3% のトップ 1 精度を達成しました。小規模なデータセットでは、BiT は ILSVRC-2012 (クラスあたり 10 例) で 76.8%、CIFAR-10 (クラスあたり 10 例) で 97.0% を達成しました。高い転写性能を実現する主要成分を詳細に分析※。
+
+## Usage tips
+
+- BiT モデルは、アーキテクチャの点で ResNetv2 と同等ですが、次の点が異なります: 1) すべてのバッチ正規化層が [グループ正規化](https://arxiv.org/abs/1803.08494) に置き換えられます。
+2) [重みの標準化](https://arxiv.org/abs/1903.10520) は畳み込み層に使用されます。著者らは、両方の組み合わせが大きなバッチサイズでのトレーニングに役立ち、重要な効果があることを示しています。
+転移学習への影響。
+
+このモデルは、[nielsr](https://huggingface.co/nielsr) によって提供されました。
+元のコードは [こちら](https://github.com/google-research/big_transfer) にあります。
+
+## Resources
+
+BiT を始めるのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示されている) リソースのリスト。
+
+ That's unfortunate. Are they trying to lose weight or are they just trying to be healthier? "]
+```
+
+## Documentation resources
+
+- [因果言語モデリング タスク ガイド](../tasks/language_modeling)
+- [翻訳タスクガイド](../tasks/translation)
+- [要約タスクガイド](../tasks/summarization)
+
+## BlenderbotConfig
+
+[[autodoc]] BlenderbotConfig
+
+## BlenderbotTokenizer
+
+[[autodoc]] BlenderbotTokenizer
+ - build_inputs_with_special_tokens
+
+## BlenderbotTokenizerFast
+
+[[autodoc]] BlenderbotTokenizerFast
+ - build_inputs_with_special_tokens
+
+## BlenderbotModel
+
+*forward* および *generate* の引数については、`transformers.BartModel`を参照してください。
+
+[[autodoc]] BlenderbotModel
+ - forward
+
+## BlenderbotForConditionalGeneration
+
+*forward* と *generate* の引数については、[`~transformers.BartForConditionalGeneration`] を参照してください。
+
+[[autodoc]] BlenderbotForConditionalGeneration
+ - forward
+
+## BlenderbotForCausalLM
+
+[[autodoc]] BlenderbotForCausalLM
+ - forward
+
+## TFBlenderbotModel
+
+[[autodoc]] TFBlenderbotModel
+ - call
+
+## TFBlenderbotForConditionalGeneration
+
+[[autodoc]] TFBlenderbotForConditionalGeneration
+ - call
+
+## FlaxBlenderbotModel
+
+[[autodoc]] FlaxBlenderbotModel
+ - __call__
+ - encode
+ - decode
+
+## FlaxBlenderbotForConditionalGeneration
+
+[[autodoc]] FlaxBlenderbotForConditionalGeneration
+ - __call__
+ - encode
+ - decode
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/blip-2.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/blip-2.md
new file mode 100644
index 0000000000000000000000000000000000000000..bd110522e27d60064580370a0cde06f91bb3a90f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/blip-2.md
@@ -0,0 +1,90 @@
+
+
+# BLIP-2
+
+## Overview
+
+BLIP-2 モデルは、[BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arxiv.org/abs/2301.12597) で提案されました。
+Junnan Li, Dongxu Li, Silvio Savarese, Steven Hoi.・サバレーゼ、スティーブン・ホイ。 BLIP-2 は、軽量の 12 層 Transformer をトレーニングすることで、フリーズされた事前トレーニング済み画像エンコーダーと大規模言語モデル (LLM) を活用します。
+それらの間にエンコーダーを配置し、さまざまな視覚言語タスクで最先端のパフォーマンスを実現します。最も注目すべき点は、BLIP-2 が 800 億パラメータ モデルである [Flamingo](https://arxiv.org/abs/2204.14198) を 8.7% 改善していることです。
+ゼロショット VQAv2 ではトレーニング可能なパラメーターが 54 分の 1 に減少します。
+
+論文の要約は次のとおりです。
+
+*大規模モデルのエンドツーエンドのトレーニングにより、視覚と言語の事前トレーニングのコストはますます法外なものになってきています。この論文では、市販の凍結済み事前トレーニング画像エンコーダと凍結された大規模言語モデルから視覚言語の事前トレーニングをブートストラップする、汎用的で効率的な事前トレーニング戦略である BLIP-2 を提案します。 BLIP-2 は、2 段階で事前トレーニングされた軽量の Querying Transformer でモダリティのギャップを橋渡しします。最初のステージでは、フリーズされた画像エンコーダーから学習する視覚言語表現をブートストラップします。第 2 段階では、凍結された言語モデルから視覚から言語への生成学習をブートストラップします。 BLIP-2 は、既存の方法よりもトレーニング可能なパラメーターが大幅に少ないにもかかわらず、さまざまな視覚言語タスクで最先端のパフォーマンスを実現します。たとえば、私たちのモデルは、トレーニング可能なパラメーターが 54 分の 1 少ないゼロショット VQAv2 で、Flamingo80B を 8.7% 上回っています。また、自然言語の命令に従うことができる、ゼロショット画像からテキストへの生成というモデルの新しい機能も実証します*
+
+ BLIP-2 アーキテクチャ。 元の論文から抜粋。
+
+このモデルは、[nielsr](https://huggingface.co/nielsr) によって提供されました。
+元のコードは [ここ](https://github.com/salesforce/LAVIS/tree/5ee63d688ba4cebff63acee04adaef2dee9af207) にあります。
+
+## Usage tips
+
+- BLIP-2 は、画像とオプションのテキスト プロンプトを指定して条件付きテキストを生成するために使用できます。推論時には、 [`generate`] メソッドを使用することをお勧めします。
+- [`Blip2Processor`] を使用してモデル用の画像を準備し、予測されたトークン ID をデコードしてテキストに戻すことができます。
+
+## Resources
+
+BLIP-2 の使用を開始するのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示されている) リソースのリスト。
+
+- 画像キャプション、ビジュアル質問応答 (VQA)、およびチャットのような会話のための BLIP-2 のデモ ノートブックは、[こちら](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/BLIP-2) にあります。
+
+ここに含めるリソースの送信に興味がある場合は、お気軽にプル リクエストを開いてください。審査させていただきます。リソースは、既存のリソースを複製するのではなく、何か新しいものを示すことが理想的です。
+
+## Blip2Config
+
+[[autodoc]] Blip2Config
+ - from_vision_qformer_text_configs
+
+## Blip2VisionConfig
+
+[[autodoc]] Blip2VisionConfig
+
+## Blip2QFormerConfig
+
+[[autodoc]] Blip2QFormerConfig
+
+## Blip2Processor
+
+[[autodoc]] Blip2Processor
+
+## Blip2VisionModel
+
+[[autodoc]] Blip2VisionModel
+ - forward
+
+## Blip2QFormerModel
+
+[[autodoc]] Blip2QFormerModel
+ - forward
+
+## Blip2Model
+
+[[autodoc]] Blip2Model
+ - forward
+ - get_text_features
+ - get_image_features
+ - get_qformer_features
+
+## Blip2ForConditionalGeneration
+
+[[autodoc]] Blip2ForConditionalGeneration
+ - forward
+ - generate
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/blip.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/blip.md
new file mode 100644
index 0000000000000000000000000000000000000000..c145af701f23bb33fc0b1fa5c705c24cf98d20c2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/blip.md
@@ -0,0 +1,134 @@
+
+
+# BLIP
+
+## Overview
+
+BLIP モデルは、[BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation](https://arxiv.org/abs/2201.12086) で Junnan Li、Dongxu Li、Caiming Xiong、Steven Hoi によって提案されました。 。
+
+BLIP は、次のようなさまざまなマルチモーダル タスクを実行できるモデルです。
+- 視覚的な質問応答
+- 画像とテキストの検索(画像とテキストのマッチング)
+- 画像キャプション
+
+論文の要約は次のとおりです。
+
+*視覚言語事前トレーニング (VLP) により、多くの視覚言語タスクのパフォーマンスが向上しました。
+ただし、既存の事前トレーニング済みモデルのほとんどは、理解ベースのタスクまたは世代ベースのタスクのいずれかでのみ優れています。さらに、最適ではない監視ソースである Web から収集されたノイズの多い画像とテキストのペアを使用してデータセットをスケールアップすることで、パフォーマンスの向上が大幅に達成されました。この論文では、視覚言語の理解と生成タスクの両方に柔軟に移行する新しい VLP フレームワークである BLIP を提案します。 BLIP は、キャプションをブートストラップすることでノイズの多い Web データを効果的に利用します。キャプショナーが合成キャプションを生成し、フィルターがノイズの多いキャプションを除去します。画像テキスト検索 (平均再現率 +2.7%@1)、画像キャプション作成 (CIDEr で +2.8%)、VQA ( VQA スコアは +1.6%)。 BLIP は、ゼロショット方式でビデオ言語タスクに直接転送した場合にも、強力な一般化能力を発揮します。コード、モデル、データセットがリリースされています。*
+
+
+
+このモデルは [ybelkada](https://huggingface.co/ybelkada) によって提供されました。
+元のコードは [ここ](https://github.com/salesforce/BLIP) にあります。
+
+## Resources
+
+- [Jupyter ノートブック](https://github.com/huggingface/notebooks/blob/main/examples/image_captioning_blip.ipynb) カスタム データセットの画像キャプション用に BLIP を微調整する方法
+
+## BlipConfig
+
+[[autodoc]] BlipConfig
+ - from_text_vision_configs
+
+## BlipTextConfig
+
+[[autodoc]] BlipTextConfig
+
+## BlipVisionConfig
+
+[[autodoc]] BlipVisionConfig
+
+## BlipProcessor
+
+[[autodoc]] BlipProcessor
+
+## BlipImageProcessor
+
+[[autodoc]] BlipImageProcessor
+ - preprocess
+
+
+
+
+## BlipModel
+
+[[autodoc]] BlipModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## BlipTextModel
+
+[[autodoc]] BlipTextModel
+ - forward
+
+## BlipVisionModel
+
+[[autodoc]] BlipVisionModel
+ - forward
+
+## BlipForConditionalGeneration
+
+[[autodoc]] BlipForConditionalGeneration
+ - forward
+
+## BlipForImageTextRetrieval
+
+[[autodoc]] BlipForImageTextRetrieval
+ - forward
+
+## BlipForQuestionAnswering
+
+[[autodoc]] BlipForQuestionAnswering
+ - forward
+
+
+
+
+## TFBlipModel
+
+[[autodoc]] TFBlipModel
+ - call
+ - get_text_features
+ - get_image_features
+
+## TFBlipTextModel
+
+[[autodoc]] TFBlipTextModel
+ - call
+
+## TFBlipVisionModel
+
+[[autodoc]] TFBlipVisionModel
+ - call
+
+## TFBlipForConditionalGeneration
+
+[[autodoc]] TFBlipForConditionalGeneration
+ - call
+
+## TFBlipForImageTextRetrieval
+
+[[autodoc]] TFBlipForImageTextRetrieval
+ - call
+
+## TFBlipForQuestionAnswering
+
+[[autodoc]] TFBlipForQuestionAnswering
+ - call
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bloom.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bloom.md
new file mode 100644
index 0000000000000000000000000000000000000000..1ac9396fa8ab76a296507474713f2d3ae90ca57f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bloom.md
@@ -0,0 +1,107 @@
+
+
+# BLOOM
+
+## Overview
+
+BLOOM モデルは、[BigScience Workshop](https://bigscience.huggingface.co/) を通じてさまざまなバージョンで提案されています。 BigScience は、研究者が時間とリソースをプールして共同でより高い効果を達成する他のオープン サイエンス イニシアチブからインスピレーションを得ています。
+BLOOM のアーキテクチャは基本的に GPT3 (次のトークン予測のための自己回帰モデル) に似ていますが、46 の異なる言語と 13 のプログラミング言語でトレーニングされています。
+モデルのいくつかの小さいバージョンが同じデータセットでトレーニングされています。 BLOOM は次のバージョンで利用できます。
+
+- [bloom-560m](https://huggingface.co/bigscience/bloom-560m)
+- [bloom-1b1](https://huggingface.co/bigscience/bloom-1b1)
+- [bloom-1b7](https://huggingface.co/bigscience/bloom-1b7)
+- [bloom-3b](https://huggingface.co/bigscience/bloom-3b)
+- [bloom-7b1](https://huggingface.co/bigscience/bloom-7b1)
+- [bloom](https://huggingface.co/bigscience/bloom) (176B parameters)
+
+## Resources
+
+BLOOM を使い始めるのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示されている) リソースのリスト。ここに含めるリソースの送信に興味がある場合は、お気軽にプル リクエストを開いてください。審査させていただきます。リソースは、既存のリソースを複製するのではなく、何か新しいものを示すことが理想的です。
+
+
+
+
+## BloomModel
+
+[[autodoc]] BloomModel
+ - forward
+
+## BloomForCausalLM
+
+[[autodoc]] BloomForCausalLM
+ - forward
+
+## BloomForSequenceClassification
+
+[[autodoc]] BloomForSequenceClassification
+ - forward
+
+## BloomForTokenClassification
+
+[[autodoc]] BloomForTokenClassification
+ - forward
+
+## BloomForQuestionAnswering
+
+[[autodoc]] BloomForQuestionAnswering
+ - forward
+
+
+
+
+## FlaxBloomModel
+
+[[autodoc]] FlaxBloomModel
+ - __call__
+
+## FlaxBloomForCausalLM
+
+[[autodoc]] FlaxBloomForCausalLM
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bort.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bort.md
new file mode 100644
index 0000000000000000000000000000000000000000..2b892a35bb9cc3a6192e1afc8af89d25c032c7d1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bort.md
@@ -0,0 +1,55 @@
+
+
+# BORT
+
+
+
+このモデルはメンテナンス モードのみであり、コードを変更する新しい PR は受け付けられません。
+
+このモデルの実行中に問題が発生した場合は、このモデルをサポートしていた最後のバージョン (v4.30.0) を再インストールしてください。
+これを行うには、コマンド `pip install -U Transformers==4.30.0` を実行します。
+
+
+
+## Overview
+
+BORT モデルは、[Optimal Subarchitecture Extraction for BERT](https://arxiv.org/abs/2010.10499) で提案されました。
+Adrian de Wynter and Daniel J. Perry.これは、BERT のアーキテクチャ パラメータの最適なサブセットです。
+著者は「ボルト」と呼んでいます。
+
+論文の要約は次のとおりです。
+
+*Devlin らから BERT アーキテクチャのアーキテクチャ パラメータの最適なサブセットを抽出します。 (2018)
+ニューラル アーキテクチャ検索のアルゴリズムにおける最近の画期的な技術を適用します。この最適なサブセットを次のように呼びます。
+"Bort" は明らかに小さく、有効 (つまり、埋め込み層を考慮しない) サイズは 5.5% です。
+オリジナルの BERT 大規模アーキテクチャ、およびネット サイズの 16%。 Bort は 288 GPU 時間で事前トレーニングすることもできます。
+最高パフォーマンスの BERT パラメトリック アーキテクチャ バリアントである RoBERTa-large の事前トレーニングに必要な時間の 1.2%
+(Liu et al., 2019)、同じマシンで BERT-large をトレーニングするのに必要な GPU 時間の世界記録の約 33%
+ハードウェア。また、CPU 上で 7.9 倍高速であるだけでなく、他の圧縮バージョンよりもパフォーマンスが優れています。
+アーキテクチャ、および一部の非圧縮バリアント: 0.3% ~ 31% のパフォーマンス向上が得られます。
+BERT-large に関して、複数の公開自然言語理解 (NLU) ベンチマークにおける絶対的な評価。*
+
+このモデルは [stefan-it](https://huggingface.co/stefan-it) によって提供されました。元のコードは[ここ](https://github.com/alexa/bort/)にあります。
+
+## Usage tips
+
+- BORT のモデル アーキテクチャは BERT に基づいています。詳細については、[BERT のドキュメント ページ](bert) を参照してください。
+ モデルの API リファレンスと使用例。
+- BORT は BERT トークナイザーの代わりに RoBERTa トークナイザーを使用します。トークナイザーの API リファレンスと使用例については、[RoBERTa のドキュメント ページ](roberta) を参照してください。
+- BORT には、 [Agora](https://adewynter.github.io/notes/bort_algorithms_and_applications.html#fine-tuning-with-algebraic-topology) と呼ばれる特定の微調整アルゴリズムが必要です。
+ 残念ながらまだオープンソース化されていません。誰かが実装しようとすると、コミュニティにとって非常に役立ちます。
+ BORT の微調整を機能させるためのアルゴリズム。
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bridgetower.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bridgetower.md
new file mode 100644
index 0000000000000000000000000000000000000000..e2ce1cb4c57709bb98a15bb00a346d3d41906dfb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bridgetower.md
@@ -0,0 +1,171 @@
+
+
+# BridgeTower
+
+## Overview
+
+BridgeTower モデルは、Xiao Xu、Chenfei Wu、Shachar Rosenman、Vasudev Lal、Wanxiang Che、Nan Duan [BridgeTower: Building Bridges Between Encoders in Vision-Language Representative Learning](https://arxiv.org/abs/2206.08657) で提案されました。ドゥアン。このモデルの目標は、
+各ユニモーダル エンコーダとクロスモーダル エンコーダの間のブリッジにより、クロスモーダル エンコーダの各層での包括的かつ詳細な対話が可能になり、追加のパフォーマンスと計算コストがほとんど無視できる程度で、さまざまな下流タスクで優れたパフォーマンスを実現します。
+
+この論文は [AAAI'23](https://aaai.org/Conferences/AAAI-23/) 会議に採択されました。
+
+論文の要約は次のとおりです。
+
+*TWO-TOWER アーキテクチャを備えたビジョン言語 (VL) モデルは、近年の視覚言語表現学習の主流となっています。
+現在の VL モデルは、軽量のユニモーダル エンコーダーを使用して、ディープ クロスモーダル エンコーダーで両方のモダリティを同時に抽出、位置合わせ、融合することを学習するか、事前にトレーニングされたディープ ユニモーダル エンコーダーから最終層のユニモーダル表現を上部のクロスモーダルエンコーダー。
+どちらのアプローチも、視覚言語表現の学習を制限し、モデルのパフォーマンスを制限する可能性があります。この論文では、ユニモーダル エンコーダの最上位層とクロスモーダル エンコーダの各層の間の接続を構築する複数のブリッジ層を導入する BRIDGETOWER を提案します。
+これにより、効果的なボトムアップのクロスモーダル調整と、クロスモーダル エンコーダー内の事前トレーニング済みユニモーダル エンコーダーのさまざまなセマンティック レベルの視覚表現とテキスト表現の間の融合が可能になります。 BRIDGETOWER は 4M 画像のみで事前トレーニングされており、さまざまな下流の視覚言語タスクで最先端のパフォーマンスを実現します。
+特に、VQAv2 テスト標準セットでは、BRIDGETOWER は 78.73% の精度を達成し、同じ事前トレーニング データとほぼ無視できる追加パラメータと計算コストで以前の最先端モデル METER を 1.09% 上回りました。
+特に、モデルをさらにスケーリングすると、BRIDGETOWER は 81.15% の精度を達成し、桁違いに大きなデータセットで事前トレーニングされたモデルを上回りました。*
+
+ ブリッジタワー アーキテクチャ。 元の論文から抜粋。
+
+このモデルは、[Anahita Bhiwandiwalla](https://huggingface.co/anahita-b)、[Tiep Le](https://huggingface.co/Tile)、[Shaoyen Tseng](https://huggingface.co/shaoyent) 。元のコードは [ここ](https://github.com/microsoft/BridgeTower) にあります。
+
+## Usage tips and examples
+
+BridgeTower は、ビジュアル エンコーダー、テキスト エンコーダー、および複数の軽量ブリッジ レイヤーを備えたクロスモーダル エンコーダーで構成されます。
+このアプローチの目標は、各ユニモーダル エンコーダーとクロスモーダル エンコーダーの間にブリッジを構築し、クロスモーダル エンコーダーの各層で包括的かつ詳細な対話を可能にすることでした。
+原則として、提案されたアーキテクチャでは、任意のビジュアル、テキスト、またはクロスモーダル エンコーダを適用できます。
+
+[`BridgeTowerProcessor`] は、[`RobertaTokenizer`] と [`BridgeTowerImageProcessor`] を単一のインスタンスにラップし、両方の機能を実現します。
+テキストをエンコードし、画像をそれぞれ用意します。
+
+次の例は、[`BridgeTowerProcessor`] と [`BridgeTowerForContrastiveLearning`] を使用して対照学習を実行する方法を示しています。
+
+```python
+>>> from transformers import BridgeTowerProcessor, BridgeTowerForContrastiveLearning
+>>> import requests
+>>> from PIL import Image
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> texts = ["An image of two cats chilling on a couch", "A football player scoring a goal"]
+
+>>> processor = BridgeTowerProcessor.from_pretrained("BridgeTower/bridgetower-large-itm-mlm-itc")
+>>> model = BridgeTowerForContrastiveLearning.from_pretrained("BridgeTower/bridgetower-large-itm-mlm-itc")
+
+>>> # forward pass
+>>> scores = dict()
+>>> for text in texts:
+... # prepare inputs
+... encoding = processor(image, text, return_tensors="pt")
+... outputs = model(**encoding)
+... scores[text] = outputs
+```
+
+次の例は、[`BridgeTowerProcessor`] と [`BridgeTowerForImageAndTextRetrieval`] を使用して画像テキストの取得を実行する方法を示しています。
+
+```python
+>>> from transformers import BridgeTowerProcessor, BridgeTowerForImageAndTextRetrieval
+>>> import requests
+>>> from PIL import Image
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> texts = ["An image of two cats chilling on a couch", "A football player scoring a goal"]
+
+>>> processor = BridgeTowerProcessor.from_pretrained("BridgeTower/bridgetower-base-itm-mlm")
+>>> model = BridgeTowerForImageAndTextRetrieval.from_pretrained("BridgeTower/bridgetower-base-itm-mlm")
+
+>>> # forward pass
+>>> scores = dict()
+>>> for text in texts:
+... # prepare inputs
+... encoding = processor(image, text, return_tensors="pt")
+... outputs = model(**encoding)
+... scores[text] = outputs.logits[0, 1].item()
+```
+
+次の例は、[`BridgeTowerProcessor`] と [`BridgeTowerForMaskedLM`] を使用してマスクされた言語モデリングを実行する方法を示しています。
+
+```python
+>>> from transformers import BridgeTowerProcessor, BridgeTowerForMaskedLM
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "http://images.cocodataset.org/val2017/000000360943.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
+>>> text = "a looking out of the window"
+
+>>> processor = BridgeTowerProcessor.from_pretrained("BridgeTower/bridgetower-base-itm-mlm")
+>>> model = BridgeTowerForMaskedLM.from_pretrained("BridgeTower/bridgetower-base-itm-mlm")
+
+>>> # prepare inputs
+>>> encoding = processor(image, text, return_tensors="pt")
+
+>>> # forward pass
+>>> outputs = model(**encoding)
+
+>>> results = processor.decode(outputs.logits.argmax(dim=-1).squeeze(0).tolist())
+
+>>> print(results)
+.a cat looking out of the window.
+```
+
+チップ:
+
+- BridgeTower のこの実装では、[`RobertaTokenizer`] を使用してテキスト埋め込みを生成し、OpenAI の CLIP/ViT モデルを使用して視覚的埋め込みを計算します。
+- 事前トレーニングされた [bridgeTower-base](https://huggingface.co/BridgeTower/bridgetower-base) および [bridgetower マスクされた言語モデリングと画像テキスト マッチング](https://huggingface.co/BridgeTower/bridgetower--base-itm-mlm) のチェックポイント がリリースされました。
+- 画像検索およびその他の下流タスクにおける BridgeTower のパフォーマンスについては、[表 5](https://arxiv.org/pdf/2206.08657.pdf) を参照してください。
+- このモデルの PyTorch バージョンは、torch 1.10 以降でのみ使用できます。
+
+## BridgeTowerConfig
+
+[[autodoc]] BridgeTowerConfig
+
+## BridgeTowerTextConfig
+
+[[autodoc]] BridgeTowerTextConfig
+
+## BridgeTowerVisionConfig
+
+[[autodoc]] BridgeTowerVisionConfig
+
+## BridgeTowerImageProcessor
+
+[[autodoc]] BridgeTowerImageProcessor
+ - preprocess
+
+## BridgeTowerProcessor
+
+[[autodoc]] BridgeTowerProcessor
+ - __call__
+
+## BridgeTowerModel
+
+[[autodoc]] BridgeTowerModel
+ - forward
+
+## BridgeTowerForContrastiveLearning
+
+[[autodoc]] BridgeTowerForContrastiveLearning
+ - forward
+
+## BridgeTowerForMaskedLM
+
+[[autodoc]] BridgeTowerForMaskedLM
+ - forward
+
+## BridgeTowerForImageAndTextRetrieval
+
+[[autodoc]] BridgeTowerForImageAndTextRetrieval
+ - forward
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bros.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bros.md
new file mode 100644
index 0000000000000000000000000000000000000000..3749a172a8286b044947acb688834ba6ffafd697
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/bros.md
@@ -0,0 +1,113 @@
+
+
+# BROS
+
+## Overview
+
+BROS モデルは、Teakgyu Hon、Donghyun Kim、Mingi Ji, Wonseok Hwang, Daehyun Nam, Sungrae Park によって [BROS: A Pre-trained Language Model Focusing on Text and Layout for Better Key Information Extraction from Documents](https://arxiv.org/abs/2108.04539) で提案されました。
+
+BROS は *BERT Relying On Spatality* の略です。これは、一連のトークンとその境界ボックスを入力として受け取り、一連の隠れ状態を出力するエンコーダー専用の Transformer モデルです。 BROS は、絶対的な空間情報を使用する代わりに、相対的な空間情報をエンコードします。
+
+BERT で使用されるトークンマスク言語モデリング目標 (TMLM) と新しいエリアマスク言語モデリング目標 (AMLM) の 2 つの目標で事前トレーニングされています。
+TMLM では、トークンはランダムにマスクされ、モデルは空間情報と他のマスクされていないトークンを使用してマスクされたトークンを予測します。
+AMLM は TMLM の 2D バージョンです。テキスト トークンをランダムにマスクし、TMLM と同じ情報で予測しますが、テキスト ブロック (領域) をマスクします。
+
+`BrosForTokenClassification`には、BrosModel の上に単純な線形層があります。各トークンのラベルを予測します。
+`BrosSpadeEEForTokenClassification`には、BrosModel の上に`initial_token_classifier`と`subsequent_token_classifier`があります。 `initial_token_classifier` は各エンティティの最初のトークンを予測するために使用され、`subsequent_token_classifier` はエンティティ内の次のトークンを予測するために使用されます。 `BrosSpadeELForTokenClassification`には BrosModel の上に`entity_linker`があります。 `entity_linker` は 2 つのエンティティ間の関係を予測するために使用されます。
+
+`BrosForTokenClassification`と`BrosSpadeEEForTokenClassification`は基本的に同じジョブを実行します。ただし、`BrosForTokenClassification`は入力トークンが完全にシリアル化されていることを前提としています (トークンは 2D 空間に存在するため、これは非常に困難な作業です)。一方、`BrosSpadeEEForTokenClassification`は 1 つのトークンから次の接続トークンを予測するため、シリアル化エラーの処理をより柔軟に行うことができます。
+
+`BrosSpadeELForTokenClassification` はエンティティ内のリンク タスクを実行します。これら 2 つのエンティティが何らかの関係を共有する場合、(あるエンティティの) 1 つのトークンから (別のエンティティの) 別のトークンへの関係を予測します。
+
+BROS は、明示的な視覚機能に依存せずに、FUNSD、SROIE、CORD、SciTSR などの Key Information Extraction (KIE) ベンチマークで同等以上の結果を達成します。
+
+論文の要約は次のとおりです。
+
+*文書画像からの重要情報抽出 (KIE) には、2 次元 (2D) 空間におけるテキストの文脈的および空間的意味論を理解する必要があります。最近の研究の多くは、文書画像の視覚的特徴とテキストおよびそのレイアウトを組み合わせることに重点を置いた事前トレーニング済み言語モデルを開発することで、この課題を解決しようとしています。一方、このペーパーでは、テキストとレイアウトの効果的な組み合わせという基本に立ち返ってこの問題に取り組みます。具体的には、BROS (BERT Relying On Spatality) という名前の事前トレーニング済み言語モデルを提案します。この言語モデルは、2D 空間内のテキストの相対位置をエンコードし、エリア マスキング戦略を使用してラベルのないドキュメントから学習します。 2D 空間内のテキストを理解するためのこの最適化されたトレーニング スキームにより、BROS は、視覚的な特徴に依存することなく、4 つの KIE ベンチマーク (FUNSD、SROIE*、CORD、および SciTSR) で以前の方法と比較して同等以上のパフォーマンスを示しました。また、この論文では、KIE タスクにおける 2 つの現実世界の課題 ((1) 間違ったテキスト順序によるエラーの最小化、および (2) 少数の下流例からの効率的な学習) を明らかにし、以前の方法に対する BROS の優位性を実証します。*
+
+このモデルは [jinho8345](https://huggingface.co/jinho8345) によって寄稿されました。元のコードは [ここ](https://github.com/clovaai/bros) にあります。
+
+## Usage tips and examples
+
+- [`~transformers.BrosModel.forward`] には、`input_ids` と `bbox` (バウンディング ボックス) が必要です。各境界ボックスは、(x0、y0、x1、y1) 形式 (左上隅、右下隅) である必要があります。境界ボックスの取得は外部 OCR システムに依存します。 「x」座標はドキュメント画像の幅で正規化する必要があり、「y」座標はドキュメント画像の高さで正規化する必要があります。
+
+```python
+def expand_and_normalize_bbox(bboxes, doc_width, doc_height):
+ # here, bboxes are numpy array
+
+ # Normalize bbox -> 0 ~ 1
+ bboxes[:, [0, 2]] = bboxes[:, [0, 2]] / width
+ bboxes[:, [1, 3]] = bboxes[:, [1, 3]] / height
+```
+
+- [`~transformers.BrosForTokenClassification.forward`、`~transformers.BrosSpadeEEForTokenClassification.forward`、`~transformers.BrosSpadeEEForTokenClassification.forward`] では、損失計算に `input_ids` と `bbox` だけでなく `box_first_token_mask` も必要です。これは、各ボックスの先頭以外のトークンを除外するためのマスクです。このマスクは、単語から `input_ids` を作成するときに境界ボックスの開始トークン インデックスを保存することで取得できます。次のコードで`box_first_token_mask`を作成できます。
+
+```python
+def make_box_first_token_mask(bboxes, words, tokenizer, max_seq_length=512):
+
+ box_first_token_mask = np.zeros(max_seq_length, dtype=np.bool_)
+
+ # encode(tokenize) each word from words (List[str])
+ input_ids_list: List[List[int]] = [tokenizer.encode(e, add_special_tokens=False) for e in words]
+
+ # get the length of each box
+ tokens_length_list: List[int] = [len(l) for l in input_ids_list]
+
+ box_end_token_indices = np.array(list(itertools.accumulate(tokens_length_list)))
+ box_start_token_indices = box_end_token_indices - np.array(tokens_length_list)
+
+ # filter out the indices that are out of max_seq_length
+ box_end_token_indices = box_end_token_indices[box_end_token_indices < max_seq_length - 1]
+ if len(box_start_token_indices) > len(box_end_token_indices):
+ box_start_token_indices = box_start_token_indices[: len(box_end_token_indices)]
+
+ # set box_start_token_indices to True
+ box_first_token_mask[box_start_token_indices] = True
+
+ return box_first_token_mask
+
+```
+
+## Resources
+
+- デモ スクリプトは [こちら](https://github.com/clovaai/bros) にあります。
+
+## BrosConfig
+
+[[autodoc]] BrosConfig
+
+## BrosProcessor
+
+[[autodoc]] BrosProcessor
+ - __call__
+
+## BrosModel
+
+[[autodoc]] BrosModel
+ - forward
+
+
+## BrosForTokenClassification
+
+[[autodoc]] BrosForTokenClassification
+ - forward
+
+## BrosSpadeEEForTokenClassification
+
+[[autodoc]] BrosSpadeEEForTokenClassification
+ - forward
+
+## BrosSpadeELForTokenClassification
+
+[[autodoc]] BrosSpadeELForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/byt5.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/byt5.md
new file mode 100644
index 0000000000000000000000000000000000000000..c6796f981817dc46eeb14f913f0cf707bc2bede1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/byt5.md
@@ -0,0 +1,154 @@
+
+
+# ByT5
+
+## Overview
+
+ByT5 モデルは、[ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir
+Kale, Adam Roberts, Colin Raffel.
+
+論文の要約は次のとおりです。
+
+*最も広く使用されている事前トレーニング済み言語モデルは、単語またはサブワード単位に対応するトークンのシーケンスで動作します。
+テキストをトークンのシーケンスとしてエンコードするには、トークナイザーが必要です。トークナイザーは通常、
+モデル。代わりに生のテキスト (バイトまたは文字) を直接操作するトークンフリー モデルには多くの利点があります。
+すぐに使用できるあらゆる言語のテキストを処理でき、ノイズに対してより堅牢であり、技術的負債を最小限に抑えます。
+複雑でエラーが発生しやすいテキスト前処理パイプラインを削除します。バイトまたは文字列がトークンより長いため
+トークンフリー モデルに関する過去の研究では、シーケンスのコストを償却するように設計された新しいモデル アーキテクチャが導入されることがよくありました。
+生のテキストを直接操作します。この論文では、標準的な Transformer アーキテクチャが次のようなもので使用できることを示します。
+バイトシーケンスを処理するための最小限の変更。パラメータ数の観点からトレードオフを注意深く特徴付けます。
+FLOP のトレーニングと推論速度を調べ、バイトレベルのモデルがトークンレベルと競合できることを示します。
+対応者。また、バイトレベルのモデルはノイズに対して大幅に堅牢であり、より優れたパフォーマンスを発揮することも示しています。
+スペルと発音に敏感なタスク。私たちの貢献の一環として、新しいセットをリリースします。
+T5 アーキテクチャに基づいた事前トレーニング済みのバイトレベルの Transformer モデルと、そこで使用されるすべてのコードとデータ
+実験。*
+
+このモデルは、[patrickvonplaten](https://huggingface.co/patrickvonplaten) によって提供されました。元のコードは次のとおりです
+[ここ](https://github.com/google-research/byt5) にあります。
+
+
+
+ByT5 のアーキテクチャは T5v1.1 モデルに基づいています。API リファレンスについては、[T5v1.1 のドキュメント ページ](t5v1.1) を参照してください。彼らは
+モデルの入力を準備する方法が異なるだけです。以下のコード例を参照してください。
+
+
+
+ByT5 は教師なしで事前トレーニングされているため、単一タスク中にタスク プレフィックスを使用する利点はありません。
+微調整。マルチタスクの微調整を行う場合は、プレフィックスを使用する必要があります。
+
+## Usage Examples
+
+ByT5 は生の UTF-8 バイトで動作するため、トークナイザーなしで使用できます。
+
+```python
+>>> from transformers import T5ForConditionalGeneration
+>>> import torch
+
+>>> model = T5ForConditionalGeneration.from_pretrained("google/byt5-small")
+
+>>> num_special_tokens = 3
+>>> # Model has 3 special tokens which take up the input ids 0,1,2 of ByT5.
+>>> # => Need to shift utf-8 character encodings by 3 before passing ids to model.
+
+>>> input_ids = torch.tensor([list("Life is like a box of chocolates.".encode("utf-8"))]) + num_special_tokens
+
+>>> labels = torch.tensor([list("La vie est comme une boîte de chocolat.".encode("utf-8"))]) + num_special_tokens
+
+>>> loss = model(input_ids, labels=labels).loss
+>>> loss.item()
+2.66
+```
+
+ただし、バッチ推論とトレーニングの場合は、トークナイザーを使用することをお勧めします。
+
+
+```python
+>>> from transformers import T5ForConditionalGeneration, AutoTokenizer
+
+>>> model = T5ForConditionalGeneration.from_pretrained("google/byt5-small")
+>>> tokenizer = AutoTokenizer.from_pretrained("google/byt5-small")
+
+>>> model_inputs = tokenizer(
+... ["Life is like a box of chocolates.", "Today is Monday."], padding="longest", return_tensors="pt"
+... )
+>>> labels_dict = tokenizer(
+... ["La vie est comme une boîte de chocolat.", "Aujourd'hui c'est lundi."], padding="longest", return_tensors="pt"
+... )
+>>> labels = labels_dict.input_ids
+
+>>> loss = model(**model_inputs, labels=labels).loss
+>>> loss.item()
+17.9
+```
+
+[T5](t5) と同様に、ByT5 はスパンマスクノイズ除去タスクでトレーニングされました。しかし、
+モデルはキャラクターに直接作用するため、事前トレーニングタスクは少し複雑です
+違う。のいくつかの文字を破損してみましょう
+`"The dog chases a ball in the park."`という文を入力し、ByT5 に予測してもらいます。
+わたしたちのため。
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+>>> import torch
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google/byt5-base")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("google/byt5-base")
+
+>>> input_ids_prompt = "The dog chases a ball in the park."
+>>> input_ids = tokenizer(input_ids_prompt).input_ids
+
+>>> # Note that we cannot add "{extra_id_...}" to the string directly
+>>> # as the Byte tokenizer would incorrectly merge the tokens
+>>> # For ByT5, we need to work directly on the character level
+>>> # Contrary to T5, ByT5 does not use sentinel tokens for masking, but instead
+>>> # uses final utf character ids.
+>>> # UTF-8 is represented by 8 bits and ByT5 has 3 special tokens.
+>>> # => There are 2**8+2 = 259 input ids and mask tokens count down from index 258.
+>>> # => mask to "The dog [258]a ball [257]park."
+
+>>> input_ids = torch.tensor([input_ids[:8] + [258] + input_ids[14:21] + [257] + input_ids[28:]])
+>>> input_ids
+tensor([[ 87, 107, 104, 35, 103, 114, 106, 35, 258, 35, 100, 35, 101, 100, 111, 111, 257, 35, 115, 100, 117, 110, 49, 1]])
+
+>>> # ByT5 produces only one char at a time so we need to produce many more output characters here -> set `max_length=100`.
+>>> output_ids = model.generate(input_ids, max_length=100)[0].tolist()
+>>> output_ids
+[0, 258, 108, 118, 35, 119, 107, 104, 35, 114, 113, 104, 35, 122, 107, 114, 35, 103, 114, 104, 118, 257, 35, 108, 113, 35, 119, 107, 104, 35, 103, 108, 118, 102, 114, 256, 108, 113, 35, 119, 107, 104, 35, 115, 100, 117, 110, 49, 35, 87, 107, 104, 35, 103, 114, 106, 35, 108, 118, 35, 119, 107, 104, 35, 114, 113, 104, 35, 122, 107, 114, 35, 103, 114, 104, 118, 35, 100, 35, 101, 100, 111, 111, 35, 108, 113, 255, 35, 108, 113, 35, 119, 107, 104, 35, 115, 100, 117, 110, 49]
+
+>>> # ^- Note how 258 descends to 257, 256, 255
+
+>>> # Now we need to split on the sentinel tokens, let's write a short loop for this
+>>> output_ids_list = []
+>>> start_token = 0
+>>> sentinel_token = 258
+>>> while sentinel_token in output_ids:
+... split_idx = output_ids.index(sentinel_token)
+... output_ids_list.append(output_ids[start_token:split_idx])
+... start_token = split_idx
+... sentinel_token -= 1
+
+>>> output_ids_list.append(output_ids[start_token:])
+>>> output_string = tokenizer.batch_decode(output_ids_list)
+>>> output_string
+['', 'is the one who does', ' in the disco', 'in the park. The dog is the one who does a ball in', ' in the park.']
+```
+
+## ByT5Tokenizer
+
+[[autodoc]] ByT5Tokenizer
+
+詳細については、[`ByT5Tokenizer`] を参照してください。
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/camembert.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/camembert.md
new file mode 100644
index 0000000000000000000000000000000000000000..db8e0aa936936d52a0e850db070b66c8bd1f2d8f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/camembert.md
@@ -0,0 +1,135 @@
+
+
+# CamemBERT
+
+## Overview
+
+CamemBERT モデルは、[CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) で提案されました。
+Louis Martin, Benjamin Muller, Pedro Javier Ortiz Suárez, Yoann Dupont, Laurent Romary, Éric Villemonte de la
+Clergerie, Djamé Seddah, and Benoît Sagot. 2019年にリリースされたFacebookのRoBERTaモデルをベースにしたモデルです。
+138GBのフランス語テキストでトレーニングされました。
+
+論文の要約は次のとおりです。
+
+*事前トレーニングされた言語モデルは現在、自然言語処理で広く普及しています。成功にもかかわらず、利用可能なほとんどの
+モデルは英語のデータ、または複数言語のデータの連結でトレーニングされています。これにより、
+このようなモデルの実際の使用は、英語を除くすべての言語で非常に限られています。フランス人にとってこの問題に対処することを目指して、
+Bi-direction Encoders for Transformers (BERT) のフランス語版である CamemBERT をリリースします。測定します
+複数の下流タスク、つまり品詞タグ付けにおける多言語モデルと比較した CamemBERT のパフォーマンス
+依存関係解析、固有表現認識、自然言語推論。 CamemBERT は最先端技術を向上させます
+検討されているほとんどのタスクに対応します。私たちは、研究と
+フランス語 NLP の下流アプリケーション。*
+
+このモデルは [camembert](https://huggingface.co/camembert) によって提供されました。元のコードは [ここ](https://camembert-model.fr/) にあります。
+
+
+
+
+この実装はRoBERTaと同じです。使用例については[RoBERTaのドキュメント](roberta)も参照してください。
+入力と出力に関する情報として。
+
+
+
+## Resources
+
+- [テキスト分類タスクガイド](../tasks/sequence_classification)
+- [トークン分類タスクガイド](../tasks/token_classification)
+- [質問回答タスク ガイド](../tasks/question_answering)
+- [因果言語モデリング タスク ガイド](../tasks/language_modeling)
+- [マスク言語モデリング タスク ガイド](../tasks/masked_language_modeling)
+- [多肢選択タスク ガイド](../tasks/multiple_choice)
+
+## CamembertConfig
+
+[[autodoc]] CamembertConfig
+
+## CamembertTokenizer
+
+[[autodoc]] CamembertTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## CamembertTokenizerFast
+
+[[autodoc]] CamembertTokenizerFast
+
+
+
+
+## CamembertModel
+
+[[autodoc]] CamembertModel
+
+## CamembertForCausalLM
+
+[[autodoc]] CamembertForCausalLM
+
+## CamembertForMaskedLM
+
+[[autodoc]] CamembertForMaskedLM
+
+## CamembertForSequenceClassification
+
+[[autodoc]] CamembertForSequenceClassification
+
+## CamembertForMultipleChoice
+
+[[autodoc]] CamembertForMultipleChoice
+
+## CamembertForTokenClassification
+
+[[autodoc]] CamembertForTokenClassification
+
+## CamembertForQuestionAnswering
+
+[[autodoc]] CamembertForQuestionAnswering
+
+
+
+
+## TFCamembertModel
+
+[[autodoc]] TFCamembertModel
+
+## TFCamembertForCasualLM
+
+[[autodoc]] TFCamembertForCausalLM
+
+## TFCamembertForMaskedLM
+
+[[autodoc]] TFCamembertForMaskedLM
+
+## TFCamembertForSequenceClassification
+
+[[autodoc]] TFCamembertForSequenceClassification
+
+## TFCamembertForMultipleChoice
+
+[[autodoc]] TFCamembertForMultipleChoice
+
+## TFCamembertForTokenClassification
+
+[[autodoc]] TFCamembertForTokenClassification
+
+## TFCamembertForQuestionAnswering
+
+[[autodoc]] TFCamembertForQuestionAnswering
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/canine.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/canine.md
new file mode 100644
index 0000000000000000000000000000000000000000..18af699967d1ad9b81edbd8cade078697f007cce
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/canine.md
@@ -0,0 +1,144 @@
+
+
+# CANINE
+
+## Overview
+
+CANINE モデルは、[CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language
+Representation](https://arxiv.org/abs/2103.06874)、Jonathan H. Clark、Dan Garrette、Iulia Turc、John Wieting 著。その
+明示的なトークン化ステップ (バイト ペアなど) を使用せずに Transformer をトレーニングする最初の論文の 1 つ
+エンコーディング (BPE、WordPiece または SentencePiece)。代わりに、モデルは Unicode 文字レベルで直接トレーニングされます。
+キャラクターレベルでのトレーニングでは必然的にシーケンスの長さが長くなりますが、CANINE はこれを効率的な方法で解決します。
+ディープ Transformer エンコーダを適用する前に、ダウンサンプリング戦略を実行します。
+
+論文の要約は次のとおりです。
+
+*パイプライン NLP システムは、エンドツーエンドのニューラル モデリングに大部分が取って代わられていますが、一般的に使用されているほぼすべてのモデルは
+依然として明示的なトークン化手順が必要です。最近のトークン化アプローチはデータ由来のサブワードに基づいていますが、
+レキシコンは手動で作成されたトークナイザーよりも脆弱ではありませんが、これらの技術はすべての言語に等しく適しているわけではありません。
+言語や固定語彙の使用により、モデルの適応能力が制限される可能性があります。この論文では、CANINE を紹介します。
+明示的なトークン化や語彙を使用せずに、文字シーケンスを直接操作するニューラル エンコーダーと、
+文字に直接作用するか、オプションでサブワードをソフト誘導バイアスとして使用する事前トレーニング戦略。
+よりきめの細かい入力を効果的かつ効率的に使用するために、CANINE はダウンサンプリングを組み合わせて、入力を削減します。
+コンテキストをエンコードするディープトランスフォーマースタックを備えたシーケンスの長さ。 CANINE は、同等の mBERT モデルよりも次の点で優れています。
+TyDi QA の 2.8 F1 は、モデル パラメータが 28% 少ないにもかかわらず、困難な多言語ベンチマークです。*
+
+このモデルは、[nielsr](https://huggingface.co/nielsr) によって提供されました。元のコードは [ここ](https://github.com/google-research/language/tree/master/language/canine) にあります。
+
+## Usage tips
+
+- CANINE は内部で少なくとも 3 つの Transformer エンコーダーを使用します: 2 つの「浅い」エンコーダー (単一のエンコーダーのみで構成)
+ レイヤー) と 1 つの「ディープ」エンコーダー (通常の BERT エンコーダー)。まず、「浅い」エンコーダを使用してコンテキストを設定します。
+ ローカル アテンションを使用した文字の埋め込み。次に、ダウンサンプリングの後、「ディープ」エンコーダーが適用されます。ついに、
+ アップサンプリング後、「浅い」エンコーダを使用して最終的な文字埋め込みが作成されます。アップと
+ ダウンサンプリングについては論文に記載されています。
+- CANINE は、デフォルトで 2048 文字の最大シーケンス長を使用します。 [`CanineTokenizer`] を使用できます
+ モデル用のテキストを準備します。
+- 特別な [CLS] トークンの最終的な非表示状態の上に線形レイヤーを配置することで分類を行うことができます。
+ (事前定義された Unicode コード ポイントがあります)。ただし、トークン分類タスクの場合は、ダウンサンプリングされたシーケンス
+ トークンは、元の文字シーケンスの長さ (2048) と一致するように再度アップサンプリングする必要があります。の
+ 詳細については、論文を参照してください。
+
+モデルのチェックポイント:
+
+ - [google/canine-c](https://huggingface.co/google/canine-c): 自己回帰文字損失で事前トレーニング済み、
+ 12 レイヤー、768 隠し、12 ヘッド、121M パラメーター (サイズ ~500 MB)。
+ - [google/canine-s](https://huggingface.co/google/canine-s): サブワード損失で事前トレーニング済み、12 層、
+ 768 個の非表示、12 ヘッド、121M パラメーター (サイズ ~500 MB)。
+
+## Usage example
+
+CANINE は生の文字で動作するため、**トークナイザーなし**で使用できます。
+
+```python
+>>> from transformers import CanineModel
+>>> import torch
+
+>>> model = CanineModel.from_pretrained("google/canine-c") # model pre-trained with autoregressive character loss
+
+>>> text = "hello world"
+>>> # use Python's built-in ord() function to turn each character into its unicode code point id
+>>> input_ids = torch.tensor([[ord(char) for char in text]])
+
+>>> outputs = model(input_ids) # forward pass
+>>> pooled_output = outputs.pooler_output
+>>> sequence_output = outputs.last_hidden_state
+```
+
+ただし、バッチ推論とトレーニングの場合は、トークナイザーを使用することをお勧めします(すべてをパディング/切り詰めるため)
+シーケンスを同じ長さにします):
+
+```python
+>>> from transformers import CanineTokenizer, CanineModel
+
+>>> model = CanineModel.from_pretrained("google/canine-c")
+>>> tokenizer = CanineTokenizer.from_pretrained("google/canine-c")
+
+>>> inputs = ["Life is like a box of chocolates.", "You never know what you gonna get."]
+>>> encoding = tokenizer(inputs, padding="longest", truncation=True, return_tensors="pt")
+
+>>> outputs = model(**encoding) # forward pass
+>>> pooled_output = outputs.pooler_output
+>>> sequence_output = outputs.last_hidden_state
+```
+
+## Resources
+
+- [テキスト分類タスクガイド](../tasks/sequence_classification)
+- [トークン分類タスクガイド](../tasks/token_classification)
+- [質問回答タスク ガイド](../tasks/question_answering)
+- [多肢選択タスク ガイド](../tasks/multiple_choice)
+
+## CanineConfig
+
+[[autodoc]] CanineConfig
+
+## CanineTokenizer
+
+[[autodoc]] CanineTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+
+## CANINE specific outputs
+
+[[autodoc]] models.canine.modeling_canine.CanineModelOutputWithPooling
+
+## CanineModel
+
+[[autodoc]] CanineModel
+ - forward
+
+## CanineForSequenceClassification
+
+[[autodoc]] CanineForSequenceClassification
+ - forward
+
+## CanineForMultipleChoice
+
+[[autodoc]] CanineForMultipleChoice
+ - forward
+
+## CanineForTokenClassification
+
+[[autodoc]] CanineForTokenClassification
+ - forward
+
+## CanineForQuestionAnswering
+
+[[autodoc]] CanineForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/chinese_clip.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/chinese_clip.md
new file mode 100644
index 0000000000000000000000000000000000000000..8d7dc401d2ae7e5c232acded8b9ccdc858c8c145
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/chinese_clip.md
@@ -0,0 +1,112 @@
+
+
+# Chinese-CLIP
+
+## Overview
+
+Chinese-CLIP An Yang, Junshu Pan, Junyang Lin, Rui Men, Yichang Zhang, Jingren Zhou, Chang Zhou [Chinese CLIP: Contrastive Vision-Language Pretraining in Chinese](https://arxiv.org/abs/2211.01335) で提案されました。周、張周。
+Chinese-CLIP は、中国語の画像とテキストのペアの大規模なデータセットに対する CLIP (Radford et al., 2021) の実装です。クロスモーダル検索を実行できるほか、ゼロショット画像分類、オープンドメインオブジェクト検出などのビジョンタスクのビジョンバックボーンとしても機能します。オリジナルの中国語-CLIPコードは[このリンクで](https://github.com/OFA-Sys/Chinese-CLIP)。
+
+論文の要約は次のとおりです。
+
+*CLIP の大成功 (Radford et al., 2021) により、視覚言語の事前訓練のための対照学習の研究と応用が促進されました。この研究では、ほとんどのデータが公開されているデータセットから取得された中国語の画像とテキストのペアの大規模なデータセットを構築し、新しいデータセットで中国語の CLIP モデルを事前トレーニングします。当社では、7,700 万から 9 億 5,800 万のパラメータにわたる、複数のサイズの 5 つの中国 CLIP モデルを開発しています。さらに、モデルのパフォーマンスを向上させるために、最初に画像エンコーダーをフリーズさせてモデルをトレーニングし、次にすべてのパラメーターを最適化してトレーニングする 2 段階の事前トレーニング方法を提案します。私たちの包括的な実験では、中国の CLIP がゼロショット学習と微調整のセットアップで MUGE、Flickr30K-CN、および COCO-CN 上で最先端のパフォーマンスを達成でき、ゼロで競争力のあるパフォーマンスを達成できることを実証しています。 - ELEVATER ベンチマークでの評価に基づくショット画像の分類 (Li et al., 2022)。コード、事前トレーニング済みモデル、デモがリリースされました。*
+
+Chinese-CLIP モデルは、[OFA-Sys](https://huggingface.co/OFA-Sys) によって提供されました。
+
+## Usage example
+
+以下のコード スニペットは、画像とテキストの特徴と類似性を計算する方法を示しています。
+
+```python
+>>> from PIL import Image
+>>> import requests
+>>> from transformers import ChineseCLIPProcessor, ChineseCLIPModel
+
+>>> model = ChineseCLIPModel.from_pretrained("OFA-Sys/chinese-clip-vit-base-patch16")
+>>> processor = ChineseCLIPProcessor.from_pretrained("OFA-Sys/chinese-clip-vit-base-patch16")
+
+>>> url = "https://clip-cn-beijing.oss-cn-beijing.aliyuncs.com/pokemon.jpeg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> # Squirtle, Bulbasaur, Charmander, Pikachu in English
+>>> texts = ["杰尼龟", "妙蛙种子", "小火龙", "皮卡丘"]
+
+>>> # compute image feature
+>>> inputs = processor(images=image, return_tensors="pt")
+>>> image_features = model.get_image_features(**inputs)
+>>> image_features = image_features / image_features.norm(p=2, dim=-1, keepdim=True) # normalize
+
+>>> # compute text features
+>>> inputs = processor(text=texts, padding=True, return_tensors="pt")
+>>> text_features = model.get_text_features(**inputs)
+>>> text_features = text_features / text_features.norm(p=2, dim=-1, keepdim=True) # normalize
+
+>>> # compute image-text similarity scores
+>>> inputs = processor(text=texts, images=image, return_tensors="pt", padding=True)
+>>> outputs = model(**inputs)
+>>> logits_per_image = outputs.logits_per_image # this is the image-text similarity score
+>>> probs = logits_per_image.softmax(dim=1) # probs: [[1.2686e-03, 5.4499e-02, 6.7968e-04, 9.4355e-01]]
+```
+
+現在、次のスケールの事前トレーニング済み Chinese-CLIP モデルが 🤗 Hub で利用可能です。
+
+- [OFA-Sys/chinese-clip-vit-base-patch16](https://huggingface.co/OFA-Sys/chinese-clip-vit-base-patch16)
+- [OFA-Sys/chinese-clip-vit-large-patch14](https://huggingface.co/OFA-Sys/chinese-clip-vit-large-patch14)
+- [OFA-Sys/chinese-clip-vit-large-patch14-336px](https://huggingface.co/OFA-Sys/chinese-clip-vit-large-patch14-336px)
+- [OFA-Sys/chinese-clip-vit-huge-patch14](https://huggingface.co/OFA-Sys/chinese-clip-vit-huge-patch14)
+
+## ChineseCLIPConfig
+
+[[autodoc]] ChineseCLIPConfig
+ - from_text_vision_configs
+
+## ChineseCLIPTextConfig
+
+[[autodoc]] ChineseCLIPTextConfig
+
+## ChineseCLIPVisionConfig
+
+[[autodoc]] ChineseCLIPVisionConfig
+
+## ChineseCLIPImageProcessor
+
+[[autodoc]] ChineseCLIPImageProcessor
+ - preprocess
+
+## ChineseCLIPFeatureExtractor
+
+[[autodoc]] ChineseCLIPFeatureExtractor
+
+## ChineseCLIPProcessor
+
+[[autodoc]] ChineseCLIPProcessor
+
+## ChineseCLIPModel
+
+[[autodoc]] ChineseCLIPModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## ChineseCLIPTextModel
+
+[[autodoc]] ChineseCLIPTextModel
+ - forward
+
+## ChineseCLIPVisionModel
+
+[[autodoc]] ChineseCLIPVisionModel
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/clap.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/clap.md
new file mode 100644
index 0000000000000000000000000000000000000000..f1e08d76018face65ab0ff4b28b03407e17bcaa8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/clap.md
@@ -0,0 +1,80 @@
+
+
+# CLAP
+
+## Overview
+
+CLAP モデルは、[Large Scale Contrastive Language-Audio pretraining with
+feature fusion and keyword-to-caption augmentation](https://arxiv.org/pdf/2211.06687.pdf)、Yusong Wu、Ke Chen、Tianyu Zhang、Yuchen Hui、Taylor Berg-Kirkpatrick、Shlomo Dubnov 著。
+
+CLAP (Contrastive Language-Audio Pretraining) は、さまざまな (音声、テキスト) ペアでトレーニングされたニューラル ネットワークです。タスクに合わせて直接最適化することなく、音声が与えられた場合に最も関連性の高いテキスト スニペットを予測するように指示できます。 CLAP モデルは、SWINTransformer を使用して log-Mel スペクトログラム入力からオーディオ特徴を取得し、RoBERTa モデルを使用してテキスト特徴を取得します。次に、テキストとオーディオの両方の特徴が、同じ次元の潜在空間に投影されます。投影されたオーディオとテキストの特徴の間のドット積が、同様のスコアとして使用されます。
+
+論文の要約は次のとおりです。
+
+*対照学習は、マルチモーダル表現学習の分野で目覚ましい成功を収めています。この論文では、音声データと自然言語記述を組み合わせて音声表現を開発する、対照的な言語音声事前トレーニングのパイプラインを提案します。この目標を達成するために、私たちはまず、さまざまなデータ ソースからの 633,526 個の音声とテキストのペアの大規模なコレクションである LAION-Audio-630K をリリースします。次に、さまざまなオーディオ エンコーダとテキスト エンコーダを考慮して、対照的な言語とオーディオの事前トレーニング モデルを構築します。機能融合メカニズムとキーワードからキャプションへの拡張をモデル設計に組み込んで、モデルが可変長の音声入力を処理できるようにし、パフォーマンスを向上させます。 3 番目に、包括的な実験を実行して、テキストから音声への取得、ゼロショット音声分類、教師付き音声分類の 3 つのタスクにわたってモデルを評価します。結果は、私たちのモデルがテキストから音声への検索タスクにおいて優れたパフォーマンスを達成していることを示しています。オーディオ分類タスクでは、モデルはゼロショット設定で最先端のパフォーマンスを達成し、非ゼロショット設定でもモデルの結果に匹敵するパフォーマンスを得ることができます。 LAION-オーディオ-6*
+
+このモデルは、[Younes Belkada](https://huggingface.co/ybelkada) および [Arthur Zucker](https://huggingface.co/ArthurZ) によって提供されました。
+元のコードは [こちら](https://github.com/LAION-AI/Clap) にあります。
+
+## ClapConfig
+
+[[autodoc]] ClapConfig
+ - from_text_audio_configs
+
+## ClapTextConfig
+
+[[autodoc]] ClapTextConfig
+
+## ClapAudioConfig
+
+[[autodoc]] ClapAudioConfig
+
+## ClapFeatureExtractor
+
+[[autodoc]] ClapFeatureExtractor
+
+## ClapProcessor
+
+[[autodoc]] ClapProcessor
+
+## ClapModel
+
+[[autodoc]] ClapModel
+ - forward
+ - get_text_features
+ - get_audio_features
+
+## ClapTextModel
+
+[[autodoc]] ClapTextModel
+ - forward
+
+## ClapTextModelWithProjection
+
+[[autodoc]] ClapTextModelWithProjection
+ - forward
+
+## ClapAudioModel
+
+[[autodoc]] ClapAudioModel
+ - forward
+
+## ClapAudioModelWithProjection
+
+[[autodoc]] ClapAudioModelWithProjection
+ - forward
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/clip.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/clip.md
new file mode 100644
index 0000000000000000000000000000000000000000..697971e9224848bab263053d388861b4d2c21e11
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/clip.md
@@ -0,0 +1,220 @@
+
+
+# CLIP
+
+## Overview
+
+CLIP モデルは、Alec Radford、Jong Wook Kim、Chris Hallacy、Aditya Ramesh、Gabriel Goh Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) で提案されました。
+サンディニ・アガルワル、ギリッシュ・サストリー、アマンダ・アスケル、パメラ・ミシュキン、ジャック・クラーク、グレッチェン・クルーガー、イリヤ・サツケヴァー。クリップ
+(Contrastive Language-Image Pre-Training) は、さまざまな (画像、テキスト) ペアでトレーニングされたニューラル ネットワークです。かもね
+直接最適化することなく、与えられた画像から最も関連性の高いテキスト スニペットを予測するように自然言語で指示されます。
+GPT-2 および 3 のゼロショット機能と同様に、タスクに対して。
+
+論文の要約は次のとおりです。
+
+*最先端のコンピューター ビジョン システムは、あらかじめ定められたオブジェクト カテゴリの固定セットを予測するようにトレーニングされています。これ
+制限された形式の監視では、指定するために追加のラベル付きデータが必要となるため、一般性と使いやすさが制限されます。
+その他の視覚的なコンセプト。画像に関する生のテキストから直接学習することは、
+より広範な監督源。どのキャプションが表示されるかを予測するという単純な事前トレーニング タスクが有効であることを示します。
+400 のデータセットで SOTA 画像表現を最初から学習するための効率的かつスケーラブルな方法はどの画像ですか
+インターネットから収集された数百万の(画像、テキスト)ペア。事前トレーニング後、自然言語を使用して参照します。
+視覚的な概念を学習し(または新しい概念を説明し)、下流のタスクへのモデルのゼロショット転送を可能にします。私たちは勉強します
+30 を超えるさまざまな既存のコンピューター ビジョン データセットでタスクをまたがってベンチマークを行うことにより、このアプローチのパフォーマンスを評価します。
+OCR、ビデオ内のアクション認識、地理的位置特定、およびさまざまな種類のきめ細かいオブジェクト分類など。の
+モデルはほとんどのタスクに簡単に移行でき、多くの場合、必要がなくても完全に監視されたベースラインと競合します。
+データセット固有のトレーニングに適しています。たとえば、ImageNet ゼロショットではオリジナルの ResNet-50 の精度と一致します。
+トレーニングに使用された 128 万のトレーニング サンプルを使用する必要はありません。コードをリリースし、事前トレーニング済み
+モデルの重みはこの https URL で確認できます。*
+
+このモデルは [valhalla](https://huggingface.co/valhalla) によって提供されました。元のコードは [ここ](https://github.com/openai/CLIP) にあります。
+
+## Usage tips and example
+
+CLIP は、マルチモーダルなビジョンおよび言語モデルです。画像とテキストの類似性やゼロショット画像に使用できます。
+分類。 CLIP は、ViT のようなトランスフォーマーを使用して視覚的特徴を取得し、因果言語モデルを使用してテキストを取得します
+特徴。次に、テキストと視覚の両方の特徴が、同じ次元の潜在空間に投影されます。ドット
+投影された画像とテキストの特徴間の積が同様のスコアとして使用されます。
+
+画像を Transformer エンコーダに供給するために、各画像は固定サイズの重複しないパッチのシーケンスに分割されます。
+これらは線形に埋め込まれます。 [CLS] トークンは、イメージ全体の表現として機能するために追加されます。作家たち
+また、絶対位置埋め込みを追加し、結果として得られるベクトルのシーケンスを標準の Transformer エンコーダに供給します。
+[`CLIPImageProcessor`] を使用して、モデルの画像のサイズ変更 (または再スケール) および正規化を行うことができます。
+
+[`CLIPTokenizer`] はテキストのエンコードに使用されます。 [`CLIPProcessor`] はラップします
+[`CLIPImageProcessor`] と [`CLIPTokenizer`] を両方の単一インスタンスに統合
+テキストをエンコードして画像を準備します。次の例は、次のメソッドを使用して画像とテキストの類似性スコアを取得する方法を示しています。
+[`CLIPProcessor`] と [`CLIPModel`]。
+
+```python
+>>> from PIL import Image
+>>> import requests
+
+>>> from transformers import CLIPProcessor, CLIPModel
+
+>>> model = CLIPModel.from_pretrained("openai/clip-vit-base-patch32")
+>>> processor = CLIPProcessor.from_pretrained("openai/clip-vit-base-patch32")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> inputs = processor(text=["a photo of a cat", "a photo of a dog"], images=image, return_tensors="pt", padding=True)
+
+>>> outputs = model(**inputs)
+>>> logits_per_image = outputs.logits_per_image # this is the image-text similarity score
+>>> probs = logits_per_image.softmax(dim=1) # we can take the softmax to get the label probabilities
+```
+
+## Resources
+
+CLIP を使い始めるのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示されている) リソースのリスト。
+
+- [リモート センシング (衛星) 画像とキャプションを使用した CLIP の微調整](https://huggingface.co/blog/fine-tune-clip-rsicd)、[RSICD データセット] を使用して CLIP を微調整する方法に関するブログ投稿(https://github.com/201528014227051/RSICD_optimal) と、データ拡張によるパフォーマンスの変化の比較。
+- この [サンプル スクリプト](https://github.com/huggingface/transformers/tree/main/examples/pytorch/contrastive-image-text) は、プレ- [COCO データセット](https://cocodataset.org/#home) を使用してトレーニングされたビジョンおよびテキスト エンコーダー。
+
+
+
+
+## CLIPModel
+
+[[autodoc]] CLIPModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## CLIPTextModel
+
+[[autodoc]] CLIPTextModel
+ - forward
+
+## CLIPTextModelWithProjection
+
+[[autodoc]] CLIPTextModelWithProjection
+ - forward
+
+## CLIPVisionModelWithProjection
+
+[[autodoc]] CLIPVisionModelWithProjection
+ - forward
+
+## CLIPVisionModel
+
+[[autodoc]] CLIPVisionModel
+ - forward
+
+
+
+
+## TFCLIPModel
+
+[[autodoc]] TFCLIPModel
+ - call
+ - get_text_features
+ - get_image_features
+
+## TFCLIPTextModel
+
+[[autodoc]] TFCLIPTextModel
+ - call
+
+## TFCLIPVisionModel
+
+[[autodoc]] TFCLIPVisionModel
+ - call
+
+
+
+
+## FlaxCLIPModel
+
+[[autodoc]] FlaxCLIPModel
+ - __call__
+ - get_text_features
+ - get_image_features
+
+## FlaxCLIPTextModel
+
+[[autodoc]] FlaxCLIPTextModel
+ - __call__
+
+## FlaxCLIPTextModelWithProjection
+
+[[autodoc]] FlaxCLIPTextModelWithProjection
+ - __call__
+
+## FlaxCLIPVisionModel
+
+[[autodoc]] FlaxCLIPVisionModel
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/clipseg.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/clipseg.md
new file mode 100644
index 0000000000000000000000000000000000000000..c8bdb0a0e4789bd86c3900224069f0cda84a5658
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/clipseg.md
@@ -0,0 +1,104 @@
+
+
+# CLIPSeg
+
+## Overview
+
+CLIPSeg モデルは、Timo Lüddecke, Alexander Ecker によって [Image Segmentation using Text and Image Prompts](https://arxiv.org/abs/2112.10003) で提案されました。
+そしてアレクサンダー・エッカー。 CLIPSeg は、ゼロショットおよびワンショット画像セグメンテーションのために、凍結された [CLIP](clip) モデルの上に最小限のデコーダを追加します。
+
+論文の要約は次のとおりです。
+
+*画像のセグメンテーションは通常、トレーニングによって解決されます。
+オブジェクト クラスの固定セットのモデル。後で追加のクラスやより複雑なクエリを組み込むとコストがかかります
+これらの式を含むデータセットでモデルを再トレーニングする必要があるためです。ここでシステムを提案します
+任意の情報に基づいて画像セグメンテーションを生成できます。
+テスト時にプロンプトが表示されます。プロンプトはテキストまたは
+画像。このアプローチにより、統一されたモデルを作成できます。
+3 つの一般的なセグメンテーション タスクについて (1 回トレーニング済み)
+参照式のセグメンテーション、ゼロショット セグメンテーション、ワンショット セグメンテーションという明確な課題が伴います。
+CLIP モデルをバックボーンとして構築し、これをトランスベースのデコーダで拡張して、高密度なデータ通信を可能にします。
+予測。の拡張バージョンでトレーニングした後、
+PhraseCut データセット、私たちのシステムは、フリーテキスト プロンプトまたは
+クエリを表す追加の画像。後者の画像ベースのプロンプトのさまざまなバリエーションを詳細に分析します。
+この新しいハイブリッド入力により、動的適応が可能になります。
+前述の 3 つのセグメンテーション タスクのみですが、
+テキストまたは画像をクエリするバイナリ セグメンテーション タスクに
+定式化することができる。最後に、システムがうまく適応していることがわかりました
+アフォーダンスまたはプロパティを含む一般化されたクエリ*
+
+ CLIPSeg の概要。 元の論文から抜粋。
+
+このモデルは、[nielsr](https://huggingface.co/nielsr) によって提供されました。
+元のコードは [ここ](https://github.com/timojl/clipseg) にあります。
+
+## Usage tips
+
+- [`CLIPSegForImageSegmentation`] は、[`CLIPSegModel`] の上にデコーダを追加します。後者は [`CLIPModel`] と同じです。
+- [`CLIPSegForImageSegmentation`] は、テスト時に任意のプロンプトに基づいて画像セグメンテーションを生成できます。プロンプトはテキストのいずれかです
+(`input_ids` としてモデルに提供される) または画像 (`conditional_pixel_values` としてモデルに提供される)。カスタムを提供することもできます
+条件付き埋め込み (`conditional_embeddings`としてモデルに提供されます)。
+
+## Resources
+
+CLIPSeg の使用を開始するのに役立つ、公式 Hugging Face およびコミュニティ (🌎 で示されている) リソースのリスト。ここに含めるリソースの送信に興味がある場合は、お気軽にプル リクエストを開いてください。審査させていただきます。リソースは、既存のリソースを複製するのではなく、何か新しいものを示すことが理想的です。
+
+
+
+Code Llama のベースとなる`Llama2`ファミリー モデルは、`bfloat16`を使用してトレーニングされましたが、元の推論では`float16`を使用します。さまざまな精度を見てみましょう。
+
+* `float32`: モデルの初期化に関する PyTorch の規約では、モデルの重みがどの `dtype` で格納されたかに関係なく、モデルを `float32` にロードします。 「transformers」も、PyTorch との一貫性を保つためにこの規則に従っています。これはデフォルトで選択されます。 `AutoModel` API でストレージの重み付けタイプを使用してチェックポイントのロードをキャストする場合は、`torch_dtype="auto"` を指定する必要があります。 `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`。
+* `bfloat16`: コード Llama はこの精度でトレーニングされているため、さらなるトレーニングや微調整に使用することをお勧めします。
+* `float16`: この精度を使用して推論を実行することをお勧めします。通常は `bfloat16` より高速であり、評価メトリクスには `bfloat16` と比べて明らかな低下が見られないためです。 bfloat16 を使用して推論を実行することもできます。微調整後、float16 と bfloat16 の両方で推論結果を確認することをお勧めします。
+
+上で述べたように、モデルを初期化するときに `torch_dtype="auto"` を使用しない限り、ストレージの重みの `dtype` はほとんど無関係です。その理由は、モデルが最初にダウンロードされ (オンラインのチェックポイントの `dtype` を使用)、次に `torch` のデフォルトの `dtype` にキャストされるためです (`torch.float32` になります)。指定された `torch_dtype` がある場合は、代わりにそれが使用されます。
+
+
+
+チップ:
+- 充填タスクはすぐにサポートされます。入力を埋めたい場所には `tokenizer.fill_token` を使用する必要があります。
+- モデル変換スクリプトは、`Llama2` ファミリの場合と同じです。
+
+使用例は次のとおりです。
+
+```bash
+python src/transformers/models/llama/convert_llama_weights_to_hf.py \
+ --input_dir /path/to/downloaded/llama/weights --model_size 7B --output_dir /output/path
+```
+
+スクリプトを実行するには、(最大のバージョンであっても) float16 精度でモデル全体をホストするのに十分な CPU RAM が必要であることに注意してください。
+いくつかのチェックポイントがあり、それぞれにモデルの各重みの一部が含まれているため、すべてを RAM にロードする必要があります)。
+
+変換後、モデルとトークナイザーは次の方法でロードできます。
+
+```python
+>>> from transformers import LlamaForCausalLM, CodeLlamaTokenizer
+
+>>> tokenizer = CodeLlamaTokenizer.from_pretrained("meta-llama/CodeLlama-7b-hf")
+>>> model = LlamaForCausalLM.from_pretrained("meta-llama/CodeLlama-7b-hf")
+>>> PROMPT = '''def remove_non_ascii(s: str) -> str:
+ """
+ return result
+'''
+>>> input_ids = tokenizer(PROMPT, return_tensors="pt")["input_ids"]
+>>> generated_ids = model.generate(input_ids, max_new_tokens=128)
+
+>>> filling = tokenizer.batch_decode(generated_ids[:, input_ids.shape[1]:], skip_special_tokens = True)[0]
+>>> print(PROMPT.replace("", filling))
+def remove_non_ascii(s: str) -> str:
+ """ Remove non-ASCII characters from a string.
+
+ Args:
+ s: The string to remove non-ASCII characters from.
+
+ Returns:
+ The string with non-ASCII characters removed.
+ """
+ result = ""
+ for c in s:
+ if ord(c) < 128:
+ result += c
+ return result
+```
+
+塗りつぶされた部分だけが必要な場合:
+
+```python
+>>> from transformers import pipeline
+>>> import torch
+
+>>> generator = pipeline("text-generation",model="meta-llama/CodeLlama-7b-hf",torch_dtype=torch.float16, device_map="auto")
+>>> generator('def remove_non_ascii(s: str) -> str:\n """ \n return result', max_new_tokens = 128)
+[{'generated_text': 'def remove_non_ascii(s: str) -> str:\n """ \n return resultRemove non-ASCII characters from a string. """\n result = ""\n for c in s:\n if ord(c) < 128:\n result += c'}]
+```
+
+内部では、トークナイザーが [`` によって自動的に分割](https://huggingface.co/docs/transformers/main/model_doc/code_llama#transformers.CodeLlamaTokenizer.fill_token) して、[ に続く書式設定された入力文字列を作成します。オリジナルのトレーニング パターン](https://github.com/facebookresearch/codellama/blob/cb51c14ec761370ba2e2bc351374a79265d0465e/llama/generation.py#L402)。これは、パターンを自分で準備するよりも堅牢です。トークンの接着など、デバッグが非常に難しい落とし穴を回避できます。このモデルまたは他のモデルに必要な CPU および GPU メモリの量を確認するには、その値を決定するのに役立つ [この計算ツール](https://huggingface.co/spaces/hf-accelerate/model-memory-usage) を試してください。
+
+LLaMA トークナイザーは、[sentencepiece](https://github.com/google/sentencepiece) に基づく BPE モデルです。センテンスピースの癖の 1 つは、シーケンスをデコードするときに、最初のトークンが単語の先頭 (例: 「Banana」) である場合、トークナイザーは文字列の先頭にプレフィックス スペースを追加しないことです。
+
+
+
+コード Llama は、`Llama2` モデルと同じアーキテクチャを持っています。API リファレンスについては、[Llama2 のドキュメント ページ](llama2) を参照してください。
+以下の Code Llama トークナイザーのリファレンスを見つけてください。
+
+
+## CodeLlamaTokenizer
+
+[[autodoc]] CodeLlamaTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## CodeLlamaTokenizerFast
+
+[[autodoc]] CodeLlamaTokenizerFast
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - update_post_processor
+ - save_vocabulary
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/codegen.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/codegen.md
new file mode 100644
index 0000000000000000000000000000000000000000..78caefe043319b58eb6f566d29eaf882812eb803
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/codegen.md
@@ -0,0 +1,90 @@
+
+
+# CodeGen
+
+## Overview
+
+
+CodeGen モデルは、[A Conversational Paradigm for Program Synthesis](https://arxiv.org/abs/2203.13474) で Erik Nijkamp、Bo Pang、林宏明、Lifu Tu、Huan Wang、Yingbo Zhou、Silvio Savarese、Caiming Xiong およびカイミン・ションさん。
+
+CodeGen は、[The Pile](https://pile.eleuther.ai/)、BigQuery、BigPython で順次トレーニングされたプログラム合成用の自己回帰言語モデルです。
+
+論文の要約は次のとおりです。
+
+*プログラム合成は、与えられた問題仕様の解決策としてコンピューター プログラムを生成することを目的としています。我々は、大規模な言語モデルを介した会話型プログラム合成アプローチを提案します。これは、従来のアプローチで直面した広大なプログラム空間とユーザーの意図の仕様を検索するという課題に対処します。私たちの新しいアプローチでは、仕様とプログラムを作成するプロセスを、ユーザーとシステムの間の複数回の対話として捉えます。これはプログラム合成をシーケンス予測問題として扱い、仕様が自然言語で表現され、目的のプログラムが条件付きでサンプリングされます。私たちは、自然言語とプログラミング言語のデータに基づいて、CodeGen と呼ばれる大規模な言語モデルのファミリーをトレーニングします。データの監視が弱く、データ サイズとモデル サイズが拡大すると、単純な自己回帰言語モデリングから会話能力が生まれます。会話型プログラム合成におけるモデルの動作を研究するために、マルチターン プログラミング ベンチマーク (MTPB) を開発します。このベンチマークでは、各問題を解決するには、ユーザーとモデル間のマルチターン会話を介したマルチステップ合成が必要です。私たちの調査結果は、会話機能の出現と、提案されている会話プログラム合成パラダイムの有効性を示しています。さらに、私たちのモデル CodeGen (TPU-v4 でトレーニングされた最大 16B パラメーターを含む) は、HumanEval ベンチマークで OpenAI の Codex を上回ります。私たちはチェックポイントを含むトレーニング ライブラリ JaxFormer をオープン ソースのコントリビューションとして利用できるようにしています: [この https URL](https://github.com/salesforce/codegen)*。
+
+このモデルは [林 宏明](https://huggingface.co/rooa) によって寄稿されました。
+元のコードは [ここ](https://github.com/salesforce/codegen) にあります。
+
+## Checkpoint Naming
+
+* CodeGen モデル [チェックポイント](https://huggingface.co/models?other=codegen) は、可変サイズのさまざまな事前トレーニング データで利用できます。
+* 形式は「Salesforce/codegen-{size}-{data}」です。ここで、
+ * `size`: `350M`、`2B`、`6B`、`16B`
+ * `data`:
+ * `nl`: パイルで事前トレーニング済み
+ * `multi`: `nl` で初期化され、複数のプログラミング言語データでさらに事前トレーニングされます。
+ * `mono`: `multi` で初期化され、Python データでさらに事前トレーニングされます。
+* たとえば、`Salesforce/codegen-350M-mono` は、Pile、複数のプログラミング言語、および Python で順次事前トレーニングされた 3 億 5,000 万のパラメーターのチェックポイントを提供します。
+
+## Usage example
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> checkpoint = "Salesforce/codegen-350M-mono"
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+
+>>> text = "def hello_world():"
+
+>>> completion = model.generate(**tokenizer(text, return_tensors="pt"))
+
+>>> print(tokenizer.decode(completion[0]))
+def hello_world():
+ print("Hello World")
+
+hello_world()
+```
+
+## Resources
+
+- [因果言語モデリング タスク ガイド](../tasks/language_modeling)
+
+## CodeGenConfig
+
+[[autodoc]] CodeGenConfig
+ - all
+
+## CodeGenTokenizer
+
+[[autodoc]] CodeGenTokenizer
+ - save_vocabulary
+
+## CodeGenTokenizerFast
+
+[[autodoc]] CodeGenTokenizerFast
+
+## CodeGenModel
+
+[[autodoc]] CodeGenModel
+ - forward
+
+## CodeGenForCausalLM
+
+[[autodoc]] CodeGenForCausalLM
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/conditional_detr.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/conditional_detr.md
new file mode 100644
index 0000000000000000000000000000000000000000..4ef09f0b6d898ec64cf6ec769e0337b8d2da7232
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/conditional_detr.md
@@ -0,0 +1,75 @@
+
+
+# Conditional DETR
+
+## Overview
+
+条件付き DETR モデルは、[Conditional DETR for Fast Training Convergence](https://arxiv.org/abs/2108.06152) で Depu Meng、Xiaokang Chen、Zejia Fan、Gang Zeng、Houqiang Li、Yuhui Yuan、Lei Sun, Jingdong Wang によって提案されました。王京東。条件付き DETR は、高速 DETR トレーニングのための条件付きクロスアテンション メカニズムを提供します。条件付き DETR は DETR よりも 6.7 倍から 10 倍速く収束します。
+
+論文の要約は次のとおりです。
+
+*最近開発された DETR アプローチは、トランスフォーマー エンコーダーおよびデコーダー アーキテクチャを物体検出に適用し、有望なパフォーマンスを実現します。この論文では、トレーニングの収束が遅いという重要な問題を扱い、高速 DETR トレーニングのための条件付きクロスアテンション メカニズムを紹介します。私たちのアプローチは、DETR におけるクロスアテンションが 4 つの四肢の位置特定とボックスの予測にコンテンツの埋め込みに大きく依存しているため、高品質のコンテンツの埋め込みの必要性が高まり、トレーニングの難易度が高くなるという点に動機づけられています。条件付き DETR と呼ばれる私たちのアプローチは、デコーダーのマルチヘッド クロスアテンションのためにデコーダーの埋め込みから条件付きの空間クエリを学習します。利点は、条件付き空間クエリを通じて、各クロスアテンション ヘッドが、個別の領域 (たとえば、1 つのオブジェクトの端またはオブジェクト ボックス内の領域) を含むバンドに注目できることです。これにより、オブジェクト分類とボックス回帰のための個別の領域をローカライズするための空間範囲が狭まり、コンテンツの埋め込みへの依存が緩和され、トレーニングが容易になります。実験結果は、条件付き DETR がバックボーン R50 および R101 で 6.7 倍速く収束し、より強力なバックボーン DC5-R50 および DC5-R101 で 10 倍速く収束することを示しています。コードは https://github.com/Atten4Vis/ConditionalDETR で入手できます。*
+
+ 条件付き DETR は、元の DETR に比べてはるかに速い収束を示します。 元の論文 から引用。
+
+このモデルは [DepuMeng](https://huggingface.co/DepuMeng) によって寄稿されました。元のコードは [ここ](https://github.com/Atten4Vis/ConditionalDETR) にあります。
+
+## Resources
+
+- [オブジェクト検出タスクガイド](../tasks/object_detection)
+
+## ConditionalDetrConfig
+
+[[autodoc]] ConditionalDetrConfig
+
+## ConditionalDetrImageProcessor
+
+[[autodoc]] ConditionalDetrImageProcessor
+ - preprocess
+ - post_process_object_detection
+ - post_process_instance_segmentation
+ - post_process_semantic_segmentation
+ - post_process_panoptic_segmentation
+
+## ConditionalDetrFeatureExtractor
+
+[[autodoc]] ConditionalDetrFeatureExtractor
+ - __call__
+ - post_process_object_detection
+ - post_process_instance_segmentation
+ - post_process_semantic_segmentation
+ - post_process_panoptic_segmentation
+
+## ConditionalDetrModel
+
+[[autodoc]] ConditionalDetrModel
+ - forward
+
+## ConditionalDetrForObjectDetection
+
+[[autodoc]] ConditionalDetrForObjectDetection
+ - forward
+
+## ConditionalDetrForSegmentation
+
+[[autodoc]] ConditionalDetrForSegmentation
+ - forward
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/convbert.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/convbert.md
new file mode 100644
index 0000000000000000000000000000000000000000..5d15f86c5136b791426efd10332b16e617d50411
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/convbert.md
@@ -0,0 +1,145 @@
+
+
+# ConvBERT
+
+
+
+## Overview
+
+ConvBERT モデルは、[ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) で Zihang Jiang、Weihao Yu、Daquan Zhou、Yunpeng Chen、Jiashi Feng、Shuicheng Yan によって提案されました。
+やん。
+
+論文の要約は次のとおりです。
+
+*BERT やそのバリアントなどの事前トレーニング済み言語モデルは、最近、さまざまな環境で目覚ましいパフォーマンスを達成しています。
+自然言語理解タスク。ただし、BERT はグローバルな自己注意ブロックに大きく依存しているため、問題が発生します。
+メモリ使用量と計算コストが大きくなります。すべての注意が入力シーケンス全体に対してクエリを実行しますが、
+グローバルな観点からアテンション マップを生成すると、一部のヘッドはローカルな依存関係のみを学習する必要があることがわかります。
+これは、計算の冗長性が存在することを意味します。したがって、我々は、新しいスパンベースの動的畳み込みを提案します。
+これらのセルフアテンション ヘッドを置き換えて、ローカルの依存関係を直接モデル化します。新しいコンボリューションヘッドと、
+自己注意の頭を休め、グローバルとローカルの両方の状況でより効率的な新しい混合注意ブロックを形成します
+学ぶ。この混合注意設計を BERT に装備し、ConvBERT モデルを構築します。実験でわかったことは、
+ConvBERT は、トレーニング コストが低く、さまざまな下流タスクにおいて BERT およびその亜種よりも大幅に優れたパフォーマンスを発揮します。
+モデルパラメータが少なくなります。注目すべきことに、ConvBERTbase モデルは 86.4 GLUE スコアを達成し、ELECTRAbase よりも 0.7 高いのに対し、
+トレーニングコストは 1/4 未満です。コードと事前トレーニングされたモデルがリリースされます。*
+
+このモデルは、[abhishek](https://huggingface.co/abhishek) によって提供されました。オリジナルの実装が見つかります
+ここ: https://github.com/yitu-opensource/ConvBert
+
+## Usage tips
+
+ConvBERT トレーニングのヒントは BERT のヒントと似ています。使用上のヒントについては、[BERT ドキュメント](bert) を参照してください。
+
+## Resources
+
+- [テキスト分類タスクガイド](../tasks/sequence_classification)
+- [トークン分類タスクガイド](../tasks/token_classification)
+- [質問回答タスク ガイド](../tasks/question_answering)
+- [マスクされた言語モデリング タスク ガイド](../tasks/masked_lang_modeling)
+- [多肢選択タスク ガイド](../tasks/multiple_choice)
+
+## ConvBertConfig
+
+[[autodoc]] ConvBertConfig
+
+## ConvBertTokenizer
+
+[[autodoc]] ConvBertTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## ConvBertTokenizerFast
+
+[[autodoc]] ConvBertTokenizerFast
+
+
+
+
+## ConvBertModel
+
+[[autodoc]] ConvBertModel
+ - forward
+
+## ConvBertForMaskedLM
+
+[[autodoc]] ConvBertForMaskedLM
+ - forward
+
+## ConvBertForSequenceClassification
+
+[[autodoc]] ConvBertForSequenceClassification
+ - forward
+
+## ConvBertForMultipleChoice
+
+[[autodoc]] ConvBertForMultipleChoice
+ - forward
+
+## ConvBertForTokenClassification
+
+[[autodoc]] ConvBertForTokenClassification
+ - forward
+
+## ConvBertForQuestionAnswering
+
+[[autodoc]] ConvBertForQuestionAnswering
+ - forward
+
+
+
+
+## TFConvBertModel
+
+[[autodoc]] TFConvBertModel
+ - call
+
+## TFConvBertForMaskedLM
+
+[[autodoc]] TFConvBertForMaskedLM
+ - call
+
+## TFConvBertForSequenceClassification
+
+[[autodoc]] TFConvBertForSequenceClassification
+ - call
+
+## TFConvBertForMultipleChoice
+
+[[autodoc]] TFConvBertForMultipleChoice
+ - call
+
+## TFConvBertForTokenClassification
+
+[[autodoc]] TFConvBertForTokenClassification
+ - call
+
+## TFConvBertForQuestionAnswering
+
+[[autodoc]] TFConvBertForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/convnext.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/convnext.md
new file mode 100644
index 0000000000000000000000000000000000000000..4386a7df8ceadb36eaaacafb5f16ced5825f3214
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/convnext.md
@@ -0,0 +1,94 @@
+
+
+# ConvNeXT
+
+## Overview
+
+ConvNeXT モデルは、[A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) で Zhuang Liu、Hanzi Mao、Chao-Yuan Wu、Christoph Feichtenhofer、Trevor Darrell、Saining Xie によって提案されました。
+ConvNeXT は、ビジョン トランスフォーマーの設計からインスピレーションを得た純粋な畳み込みモデル (ConvNet) であり、ビジョン トランスフォーマーよりも優れたパフォーマンスを発揮すると主張しています。
+
+論文の要約は次のとおりです。
+
+*視覚認識の「狂騒の 20 年代」は、最先端の画像分類モデルとして ConvNet にすぐに取って代わられた Vision Transformers (ViT) の導入から始まりました。
+一方、バニラ ViT は、オブジェクト検出やセマンティック セグメンテーションなどの一般的なコンピューター ビジョン タスクに適用すると困難に直面します。階層型トランスフォーマーです
+(Swin Transformers など) は、いくつかの ConvNet の以前の機能を再導入し、Transformers を汎用ビジョン バックボーンとして実用的に可能にし、幅広い環境で顕著なパフォーマンスを実証しました。
+さまざまな視覚タスク。ただし、このようなハイブリッド アプローチの有効性は、依然として、固有の誘導性ではなく、トランスフォーマーの本質的な優位性によるところが大きいと考えられています。
+畳み込みのバイアス。この作業では、設計空間を再検討し、純粋な ConvNet が達成できる限界をテストします。標準 ResNet を設計に向けて徐々に「最新化」します。
+ビジョン Transformer の概要を確認し、途中でパフォーマンスの違いに寄与するいくつかの重要なコンポーネントを発見します。この調査の結果は、純粋な ConvNet モデルのファミリーです。
+ConvNextと呼ばれます。 ConvNeXts は完全に標準の ConvNet モジュールから構築されており、精度と拡張性の点で Transformers と有利に競合し、87.8% の ImageNet トップ 1 精度を達成しています。
+標準 ConvNet のシンプルさと効率を維持しながら、COCO 検出と ADE20K セグメンテーションでは Swin Transformers よりも優れたパフォーマンスを発揮します。*
+
+ ConvNeXT アーキテクチャ。 元の論文 から抜粋。
+
+このモデルは、[nielsr](https://huggingface.co/nielsr) によって提供されました。 TensorFlow バージョンのモデルは [ariG23498](https://github.com/ariG23498) によって提供されました。
+[gante](https://github.com/gante)、および [sayakpaul](https://github.com/sayakpaul) (同等の貢献)。元のコードは [こちら](https://github.com/facebookresearch/ConvNeXt) にあります。
+
+## Resources
+
+ConvNeXT の使用を開始するのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示される) リソースのリスト。
+
+
+
+
+## ConvNextModel
+
+[[autodoc]] ConvNextModel
+ - forward
+
+## ConvNextForImageClassification
+
+[[autodoc]] ConvNextForImageClassification
+ - forward
+
+
+
+
+## TFConvNextModel
+
+[[autodoc]] TFConvNextModel
+ - call
+
+## TFConvNextForImageClassification
+
+[[autodoc]] TFConvNextForImageClassification
+ - call
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/convnextv2.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/convnextv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..9e4d54df24b1c17659367773f40e73e8cc85a93c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/convnextv2.md
@@ -0,0 +1,68 @@
+
+
+# ConvNeXt V2
+
+## Overview
+
+ConvNeXt V2 モデルは、Sanghyun Woo、Shobhik Debnath、Ronghang Hu、Xinlei Chen、Zhuang Liu, In So Kweon, Saining Xie. によって [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) で提案されました。
+ConvNeXt V2 は、Vision Transformers の設計からインスピレーションを得た純粋な畳み込みモデル (ConvNet) であり、[ConvNeXT](convnext) の後継です。
+
+論文の要約は次のとおりです。
+
+*アーキテクチャの改善と表現学習フレームワークの改善により、視覚認識の分野は 2020 年代初頭に急速な近代化とパフォーマンスの向上を実現しました。たとえば、ConvNeXt に代表される最新の ConvNet は、さまざまなシナリオで強力なパフォーマンスを実証しています。これらのモデルはもともと ImageNet ラベルを使用した教師あり学習用に設計されましたが、マスク オートエンコーダー (MAE) などの自己教師あり学習手法からも潜在的に恩恵を受けることができます。ただし、これら 2 つのアプローチを単純に組み合わせると、パフォーマンスが標準以下になることがわかりました。この論文では、完全畳み込みマスク オートエンコーダ フレームワークと、チャネル間の機能競合を強化するために ConvNeXt アーキテクチャに追加できる新しい Global Response Normalization (GRN) 層を提案します。この自己教師あり学習手法とアーキテクチャの改善の共同設計により、ConvNeXt V2 と呼ばれる新しいモデル ファミリが誕生しました。これにより、ImageNet 分類、COCO 検出、ADE20K セグメンテーションなどのさまざまな認識ベンチマークにおける純粋な ConvNet のパフォーマンスが大幅に向上します。また、ImageNet でトップ 1 の精度 76.7% を誇る効率的な 370 万パラメータの Atto モデルから、最先端の 88.9% を達成する 650M Huge モデルまで、さまざまなサイズの事前トレーニング済み ConvNeXt V2 モデルも提供しています。公開トレーニング データのみを使用した精度*。
+
+ ConvNeXt V2 アーキテクチャ。 元の論文 から抜粋。
+
+このモデルは [adirik](https://huggingface.co/adirik) によって提供されました。元のコードは [こちら](https://github.com/facebookresearch/ConvNeXt-V2) にあります。
+
+## Resources
+
+ConvNeXt V2 の使用を開始するのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示される) リソースのリスト。
+
+
+
+CPM のアーキテクチャは、トークン化方法を除いて GPT-2 と同じです。詳細については、[GPT-2 ドキュメント](openai-community/gpt2) を参照してください。
+API リファレンス情報。
+
+
+
+## CpmTokenizer
+
+[[autodoc]] CpmTokenizer
+
+## CpmTokenizerFast
+
+[[autodoc]] CpmTokenizerFast
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/cpmant.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/cpmant.md
new file mode 100644
index 0000000000000000000000000000000000000000..ca1f65caa16c045c2a22838682dd03d3af7f897f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/cpmant.md
@@ -0,0 +1,47 @@
+
+
+# CPMAnt
+
+## Overview
+
+CPM-Ant は、10B パラメータを備えたオープンソースの中国語の事前トレーニング済み言語モデル (PLM) です。これは、CPM-Live のライブ トレーニング プロセスの最初のマイルストーンでもあります。トレーニングプロセスは費用対効果が高く、環境に優しいものです。 CPM-Ant は、CUGE ベンチマークでのデルタ チューニングでも有望な結果を達成しています。フル モデルに加えて、さまざまなハードウェア構成の要件を満たすさまざまな圧縮バージョンも提供しています。 [詳細を見る](https://github.com/OpenBMB/CPM-Live/tree/cpm-ant/cpm-live)
+
+このモデルは [OpenBMB](https://huggingface.co/openbmb) によって提供されました。元のコードは [ここ](https://github.com/OpenBMB/CPM-Live/tree/cpm-ant/cpm-live) にあります。
+
+## Resources
+
+- [CPM-Live](https://github.com/OpenBMB/CPM-Live/tree/cpm-ant/cpm-live) に関するチュートリアル。
+
+## CpmAntConfig
+
+[[autodoc]] CpmAntConfig
+ - all
+
+## CpmAntTokenizer
+
+[[autodoc]] CpmAntTokenizer
+ - all
+
+## CpmAntModel
+
+[[autodoc]] CpmAntModel
+ - all
+
+## CpmAntForCausalLM
+
+[[autodoc]] CpmAntForCausalLM
+ - all
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/ctrl.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/ctrl.md
new file mode 100644
index 0000000000000000000000000000000000000000..f93345d30e79bc6b16fb5fb5e7acbb3e82744125
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/ctrl.md
@@ -0,0 +1,113 @@
+
+
+# CTRL
+
+
+
+## Overview
+
+CTRL モデルは、Nitish Shirish Keskar*、Bryan McCann*、Lav R. Varshney、Caiming Xiong, Richard Socher によって [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) で提案されました。
+リチャード・ソーチャー。これは、非常に大規模なコーパスの言語モデリングを使用して事前トレーニングされた因果的 (一方向) トランスフォーマーです
+最初のトークンが制御コード (リンク、書籍、Wikipedia など) として予約されている、約 140 GB のテキスト データ。
+
+論文の要約は次のとおりです。
+
+*大規模な言語モデルは有望なテキスト生成機能を示していますが、ユーザーは特定の言語モデルを簡単に制御できません
+生成されたテキストの側面。 16 億 3,000 万パラメータの条件付きトランスフォーマー言語モデルである CTRL をリリースします。
+スタイル、コンテンツ、タスク固有の動作を制御する制御コードを条件付けるように訓練されています。制御コードは
+生のテキストと自然に共生する構造から派生し、教師なし学習の利点を維持しながら、
+テキスト生成をより明示的に制御できるようになります。これらのコードを使用すると、CTRL でどの部分が予測されるのかを予測することもできます。
+トレーニング データにはシーケンスが与えられる可能性が最も高くなります。これにより、大量のデータを分析するための潜在的な方法が提供されます。
+モデルベースのソース帰属を介して。*
+
+このモデルは、[keskarnitishr](https://huggingface.co/keskarnitishr) によって提供されました。元のコードが見つかる
+[こちら](https://github.com/salesforce/Salesforce/ctrl)。
+
+## Usage tips
+
+- CTRL は制御コードを利用してテキストを生成します。生成を特定の単語や文で開始する必要があります。
+ またはリンクして一貫したテキストを生成します。 [元の実装](https://github.com/salesforce/Salesforce/ctrl) を参照してください。
+ 詳しくは。
+- CTRL は絶対位置埋め込みを備えたモデルであるため、通常は入力を右側にパディングすることをお勧めします。
+ 左。
+- CTRL は因果言語モデリング (CLM) の目的でトレーニングされているため、次の予測に強力です。
+ シーケンス内のトークン。この機能を利用すると、CTRL は構文的に一貫したテキストを生成できるようになります。
+ *run_generation.py* サンプル スクリプトで確認できます。
+- PyTorch モデルは、以前に計算されたキーと値のアテンション ペアである`past_key_values`を入力として受け取ることができます。
+ TensorFlow モデルは`past`を入力として受け入れます。 `past_key_values`値を使用すると、モデルが再計算されなくなります。
+ テキスト生成のコンテキストで事前に計算された値。 [`forward`](model_doc/ctrl#transformers.CTRLModel.forward) を参照してください。
+ この引数の使用法の詳細については、メソッドを参照してください。
+
+## Resources
+
+- [テキスト分類タスクガイド](../tasks/sequence_classification)
+- [因果言語モデリング タスク ガイド](../tasks/language_modeling)
+
+## CTRLConfig
+
+[[autodoc]] CTRLConfig
+
+## CTRLTokenizer
+
+[[autodoc]] CTRLTokenizer
+ - save_vocabulary
+
+
+
+
+## CTRLModel
+
+[[autodoc]] CTRLModel
+ - forward
+
+## CTRLLMHeadModel
+
+[[autodoc]] CTRLLMHeadModel
+ - forward
+
+## CTRLForSequenceClassification
+
+[[autodoc]] CTRLForSequenceClassification
+ - forward
+
+
+
+
+## TFCTRLModel
+
+[[autodoc]] TFCTRLModel
+ - call
+
+## TFCTRLLMHeadModel
+
+[[autodoc]] TFCTRLLMHeadModel
+ - call
+
+## TFCTRLForSequenceClassification
+
+[[autodoc]] TFCTRLForSequenceClassification
+ - call
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/cvt.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/cvt.md
new file mode 100644
index 0000000000000000000000000000000000000000..16d39d1b55d35cf3a067b2ea1efcc5247ee89827
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/cvt.md
@@ -0,0 +1,88 @@
+
+
+# Convolutional Vision Transformer (CvT)
+
+## Overview
+
+CvT モデルは、Haping Wu、Bin Xiao、Noel Codella、Mengchen Liu、Xiyang Dai、Lu Yuan、Lei Zhang によって [CvT: Introduction Convolutions to Vision Transformers](https://arxiv.org/abs/2103.15808) で提案されました。畳み込みビジョン トランスフォーマー (CvT) は、ViT に畳み込みを導入して両方の設計の長所を引き出すことにより、[ビジョン トランスフォーマー (ViT)](vit) のパフォーマンスと効率を向上させます。
+
+論文の要約は次のとおりです。
+
+*この論文では、ビジョン トランスフォーマー (ViT) を改善する、畳み込みビジョン トランスフォーマー (CvT) と呼ばれる新しいアーキテクチャを紹介します。
+ViT に畳み込みを導入して両方の設計の長所を引き出すことで、パフォーマンスと効率を向上させます。これは次のようにして実現されます。
+2 つの主要な変更: 新しい畳み込みトークンの埋め込みを含むトランスフォーマーの階層と、畳み込みトランスフォーマー
+畳み込み射影を利用したブロック。これらの変更により、畳み込みニューラル ネットワーク (CNN) の望ましい特性が導入されます。
+トランスフォーマーの利点 (動的な注意力、
+グローバルなコンテキストとより良い一般化)。私たちは広範な実験を実施することで CvT を検証し、このアプローチが達成できることを示しています。
+ImageNet-1k 上の他のビジョン トランスフォーマーや ResNet よりも、パラメータが少なく、FLOP が低い、最先端のパフォーマンスを実現します。加えて、
+より大きなデータセット (例: ImageNet-22k) で事前トレーニングし、下流のタスクに合わせて微調整すると、パフォーマンスの向上が維持されます。事前トレーニング済み
+ImageNet-22k、当社の CvT-W24 は、ImageNet-1k val set で 87.7\% というトップ 1 の精度を獲得しています。最後に、私たちの結果は、位置エンコーディングが、
+既存のビジョン トランスフォーマーの重要なコンポーネントであるこのコンポーネントは、モデルでは安全に削除できるため、高解像度のビジョン タスクの設計が簡素化されます。*
+
+このモデルは [anugunj](https://huggingface.co/anugunj) によって提供されました。元のコードは [ここ](https://github.com/microsoft/CvT) にあります。
+
+## Usage tips
+
+- CvT モデルは通常の Vision Transformer ですが、畳み込みでトレーニングされています。 ImageNet-1K および CIFAR-100 で微調整すると、[オリジナル モデル (ViT)](vit) よりも優れたパフォーマンスを発揮します。
+- カスタム データの微調整だけでなく推論に関するデモ ノートブックも [ここ](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/VisionTransformer) で確認できます ([`ViTFeatureExtractor を置き換えるだけで済みます) `] による [`AutoImageProcessor`] および [`ViTForImageClassification`] による [`CvtForImageClassification`])。
+- 利用可能なチェックポイントは、(1) [ImageNet-22k](http://www.image-net.org/) (1,400 万の画像と 22,000 のクラスのコレクション) でのみ事前トレーニングされている、(2) も問題ありません。 ImageNet-22k で調整、または (3) [ImageNet-1k](http://www.image-net.org/challenges/LSVRC/2012/) (ILSVRC 2012 とも呼ばれるコレクション) でも微調整130万の
+ 画像と 1,000 クラス)。
+
+## Resources
+
+CvT を始めるのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示される) リソースのリスト。
+
+
+
+
+## CvtModel
+
+[[autodoc]] CvtModel
+ - forward
+
+## CvtForImageClassification
+
+[[autodoc]] CvtForImageClassification
+ - forward
+
+
+
+
+## TFCvtModel
+
+[[autodoc]] TFCvtModel
+ - call
+
+## TFCvtForImageClassification
+
+[[autodoc]] TFCvtForImageClassification
+ - call
+
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/data2vec.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/data2vec.md
new file mode 100644
index 0000000000000000000000000000000000000000..78ae71e6947e4d9720737dc0547c719c779ddd20
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/data2vec.md
@@ -0,0 +1,187 @@
+
+
+# Data2Vec
+
+## Overview
+
+Data2Vec モデルは、[data2vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/pdf/2202.03555) で Alexei Baevski、Wei-Ning Hsu、Qiantong Xu、バArun Babu, Jiatao Gu and Michael Auli.
+Data2Vec は、テキスト、音声、画像などのさまざまなデータ モダリティにわたる自己教師あり学習のための統一フレームワークを提案します。
+重要なのは、事前トレーニングの予測ターゲットは、モダリティ固有のコンテキストに依存しないターゲットではなく、入力のコンテキスト化された潜在表現であることです。
+
+論文の要約は次のとおりです。
+
+*自己教師あり学習の一般的な考え方はどのモダリティでも同じですが、実際のアルゴリズムと
+単一のモダリティを念頭に置いて開発されたため、目的は大きく異なります。一般に近づけるために
+自己教師あり学習では、どちらの音声に対しても同じ学習方法を使用するフレームワークである data2vec を紹介します。
+NLP またはコンピューター ビジョン。中心となるアイデアは、完全な入力データの潜在的な表現を、
+標準の Transformer アーキテクチャを使用した自己蒸留セットアップの入力のマスクされたビュー。
+単語、視覚的トークン、人間の音声単位などのモダリティ固有のターゲットを予測するのではなく、
+本質的にローカルであるため、data2vec は、からの情報を含む文脈化された潜在表現を予測します。
+入力全体。音声認識、画像分類、および
+自然言語理解は、新しい最先端技術や、主流のアプローチに匹敵するパフォーマンスを実証します。
+モデルとコードは、www.github.com/pytorch/fairseq/tree/master/examples/data2vec.* で入手できます。
+
+このモデルは、[edugp](https://huggingface.co/edugp) および [patrickvonplaten](https://huggingface.co/patrickvonplaten) によって提供されました。
+[sayakpaul](https://github.com/sayakpaul) と [Rocketknight1](https://github.com/Rocketknight1) は、TensorFlow のビジョンに Data2Vec を提供しました。
+
+元のコード (NLP および音声用) は、[こちら](https://github.com/pytorch/fairseq/tree/main/examples/data2vec) にあります。
+ビジョンの元のコードは [こちら](https://github.com/facebookresearch/data2vec_vision/tree/main/beit) にあります。
+
+## Usage tips
+
+- Data2VecAudio、Data2VecText、および Data2VecVision はすべて、同じ自己教師あり学習方法を使用してトレーニングされています。
+- Data2VecAudio の場合、前処理は特徴抽出を含めて [`Wav2Vec2Model`] と同じです。
+- Data2VecText の場合、前処理はトークン化を含めて [`RobertaModel`] と同じです。
+- Data2VecVision の場合、前処理は特徴抽出を含めて [`BeitModel`] と同じです。
+
+## Resources
+
+Data2Vec の使用を開始するのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示される) リソースのリスト。
+
+
+
+
+## Data2VecAudioModel
+
+[[autodoc]] Data2VecAudioModel
+ - forward
+
+## Data2VecAudioForAudioFrameClassification
+
+[[autodoc]] Data2VecAudioForAudioFrameClassification
+ - forward
+
+## Data2VecAudioForCTC
+
+[[autodoc]] Data2VecAudioForCTC
+ - forward
+
+## Data2VecAudioForSequenceClassification
+
+[[autodoc]] Data2VecAudioForSequenceClassification
+ - forward
+
+## Data2VecAudioForXVector
+
+[[autodoc]] Data2VecAudioForXVector
+ - forward
+
+## Data2VecTextModel
+
+[[autodoc]] Data2VecTextModel
+ - forward
+
+## Data2VecTextForCausalLM
+
+[[autodoc]] Data2VecTextForCausalLM
+ - forward
+
+## Data2VecTextForMaskedLM
+
+[[autodoc]] Data2VecTextForMaskedLM
+ - forward
+
+## Data2VecTextForSequenceClassification
+
+[[autodoc]] Data2VecTextForSequenceClassification
+ - forward
+
+## Data2VecTextForMultipleChoice
+
+[[autodoc]] Data2VecTextForMultipleChoice
+ - forward
+
+## Data2VecTextForTokenClassification
+
+[[autodoc]] Data2VecTextForTokenClassification
+ - forward
+
+## Data2VecTextForQuestionAnswering
+
+[[autodoc]] Data2VecTextForQuestionAnswering
+ - forward
+
+## Data2VecVisionModel
+
+[[autodoc]] Data2VecVisionModel
+ - forward
+
+## Data2VecVisionForImageClassification
+
+[[autodoc]] Data2VecVisionForImageClassification
+ - forward
+
+## Data2VecVisionForSemanticSegmentation
+
+[[autodoc]] Data2VecVisionForSemanticSegmentation
+ - forward
+
+
+
+
+## TFData2VecVisionModel
+
+[[autodoc]] TFData2VecVisionModel
+ - call
+
+## TFData2VecVisionForImageClassification
+
+[[autodoc]] TFData2VecVisionForImageClassification
+ - call
+
+## TFData2VecVisionForSemanticSegmentation
+
+[[autodoc]] TFData2VecVisionForSemanticSegmentation
+ - call
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deberta-v2.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deberta-v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..35da9d0a1d584ff1013825d463c0b6cee03b2260
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deberta-v2.md
@@ -0,0 +1,167 @@
+
+
+# DeBERTa-v2
+
+## Overview
+
+DeBERTa モデルは、Pengcheng He、Xiaodong Liu、Jianfeng Gao、Weizhu Chen によって [DeBERTa: Decoding-enhanced BERT with Disentangled Attendant](https://arxiv.org/abs/2006.03654) で提案されました。Google のモデルに基づいています。
+2018年にリリースされたBERTモデルと2019年にリリースされたFacebookのRoBERTaモデル。
+
+これは、もつれた注意を解きほぐし、使用されるデータの半分を使用して強化されたマスク デコーダ トレーニングを備えた RoBERTa に基づいて構築されています。
+ロベルタ。
+
+論文の要約は次のとおりです。
+
+*事前トレーニングされたニューラル言語モデルの最近の進歩により、多くの自然言語モデルのパフォーマンスが大幅に向上しました。
+言語処理 (NLP) タスク。この論文では、新しいモデル アーキテクチャ DeBERTa (Decoding-enhanced BERT with
+これは、2 つの新しい技術を使用して BERT モデルと RoBERTa モデルを改善します。 1つ目は、
+もつれを解く注意メカニズム。各単語は、その内容をエンコードする 2 つのベクトルを使用して表現され、
+単語間の注意の重みは、それらの単語のもつれ解除行列を使用して計算されます。
+内容と相対的な位置。 2 番目に、強化されたマスク デコーダを使用して、出力ソフトマックス レイヤを次のように置き換えます。
+モデルの事前トレーニング用にマスクされたトークンを予測します。これら 2 つの手法により効率が大幅に向上することを示します。
+モデルの事前トレーニングと下流タスクのパフォーマンスの向上。 RoBERTa-Large と比較すると、DeBERTa モデルは半分のレベルでトレーニングされています。
+トレーニング データは幅広い NLP タスクで一貫して優れたパフォーマンスを示し、MNLI で +0.9% の改善を達成しました。
+(90.2% 対 91.1%)、SQuAD v2.0 では +2.3% (88.4% 対 90.7%)、RACE では +3.6% (83.2% 対 86.8%) でした。 DeBERTa コードと
+事前トレーニングされたモデルは https://github.com/microsoft/DeBERTa で公開されます。*
+
+次の情報は、[元の実装で直接表示されます リポジトリ](https://github.com/microsoft/DeBERTa)。 DeBERTa v2 は、DeBERTa モデルの 2 番目のバージョンです。それには以下が含まれます
+SuperGLUE 単一モデルの提出に使用された 1.5B モデルは、人間のベースライン 89.8 に対して 89.9 を達成しました。あなたはできる
+この投稿に関する詳細については、著者のドキュメントを参照してください。
+[ブログ](https://www.microsoft.com/en-us/research/blog/microsoft-deberta-surpasses-human-performance-on-the-superglue-benchmark/)
+
+v2 の新機能:
+
+- **語彙** v2 では、トレーニング データから構築されたサイズ 128K の新しい語彙を使用するようにトークナイザーが変更されました。
+ GPT2 ベースのトークナイザーの代わりに、トークナイザーは
+ [sentencepiece ベース](https://github.com/google/sentencepiece) トークナイザー。
+- **nGiE(nGram Induced Input Encoding)** DeBERTa-v2 モデルは、最初の畳み込み層とは別に追加の畳み込み層を使用します。
+ トランスフォーマー層を使用して、入力トークンのローカル依存関係をよりよく学習します。
+- **位置射影行列を注目レイヤーのコンテンツ射影行列と共有** 以前に基づく
+ 実験では、パフォーマンスに影響を与えることなくパラメータを保存できます。
+- **バケットを適用して相対位置をエンコードします** DeBERTa-v2 モデルはログ バケットを使用して相対位置をエンコードします
+ T5に似ています。
+- **900M モデル & 1.5B モデル** 2 つの追加モデル サイズ: 900M と 1.5B が利用可能で、これにより、パフォーマンスが大幅に向上します。
+ 下流タスクのパフォーマンス。
+
+このモデルは [DeBERTa](https://huggingface.co/DeBERTa) によって寄稿されました。このモデルの TF 2.0 実装は、
+[kamalkraj](https://huggingface.co/kamalkraj) による投稿。元のコードは [こちら](https://github.com/microsoft/DeBERTa) にあります。
+
+## Resources
+- [テキスト分類タスクガイド](../tasks/sequence_classification)
+- [トークン分類タスクガイド](../tasks/token_classification)
+- [質問回答タスク ガイド](../tasks/question_answering)
+- [マスク言語モデリング タスク ガイド](../tasks/masked_language_modeling)
+- [多肢選択タスク ガイド](../tasks/multiple_choice)
+
+## DebertaV2Config
+
+[[autodoc]] DebertaV2Config
+
+## DebertaV2Tokenizer
+
+[[autodoc]] DebertaV2Tokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## DebertaV2TokenizerFast
+
+[[autodoc]] DebertaV2TokenizerFast
+ - build_inputs_with_special_tokens
+ - create_token_type_ids_from_sequences
+
+
+
+
+## DebertaV2Model
+
+[[autodoc]] DebertaV2Model
+ - forward
+
+## DebertaV2PreTrainedModel
+
+[[autodoc]] DebertaV2PreTrainedModel
+ - forward
+
+## DebertaV2ForMaskedLM
+
+[[autodoc]] DebertaV2ForMaskedLM
+ - forward
+
+## DebertaV2ForSequenceClassification
+
+[[autodoc]] DebertaV2ForSequenceClassification
+ - forward
+
+## DebertaV2ForTokenClassification
+
+[[autodoc]] DebertaV2ForTokenClassification
+ - forward
+
+## DebertaV2ForQuestionAnswering
+
+[[autodoc]] DebertaV2ForQuestionAnswering
+ - forward
+
+## DebertaV2ForMultipleChoice
+
+[[autodoc]] DebertaV2ForMultipleChoice
+ - forward
+
+
+
+
+## TFDebertaV2Model
+
+[[autodoc]] TFDebertaV2Model
+ - call
+
+## TFDebertaV2PreTrainedModel
+
+[[autodoc]] TFDebertaV2PreTrainedModel
+ - call
+
+## TFDebertaV2ForMaskedLM
+
+[[autodoc]] TFDebertaV2ForMaskedLM
+ - call
+
+## TFDebertaV2ForSequenceClassification
+
+[[autodoc]] TFDebertaV2ForSequenceClassification
+ - call
+
+## TFDebertaV2ForTokenClassification
+
+[[autodoc]] TFDebertaV2ForTokenClassification
+ - call
+
+## TFDebertaV2ForQuestionAnswering
+
+[[autodoc]] TFDebertaV2ForQuestionAnswering
+ - call
+
+## TFDebertaV2ForMultipleChoice
+
+[[autodoc]] TFDebertaV2ForMultipleChoice
+ - call
+
+
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deberta.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deberta.md
new file mode 100644
index 0000000000000000000000000000000000000000..f7e00ad3b2bccea9fbff45604be048a9c5642f4c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deberta.md
@@ -0,0 +1,164 @@
+
+
+# DeBERTa
+
+## Overview
+
+DeBERTa モデルは、Pengcheng He、Xiaodong Liu、Jianfeng Gao、Weizhu Chen によって [DeBERTa: Decoding-enhanced BERT with Disentangled Attendant](https://arxiv.org/abs/2006.03654) で提案されました。Google のモデルに基づいています。
+2018年にリリースされたBERTモデルと2019年にリリースされたFacebookのRoBERTaモデル。
+
+これは、もつれた注意を解きほぐし、使用されるデータの半分を使用して強化されたマスク デコーダ トレーニングを備えた RoBERTa に基づいて構築されています。
+ロベルタ。
+
+論文の要約は次のとおりです。
+
+*事前トレーニングされたニューラル言語モデルの最近の進歩により、多くの自然言語モデルのパフォーマンスが大幅に向上しました。
+言語処理 (NLP) タスク。この論文では、新しいモデル アーキテクチャ DeBERTa (Decoding-enhanced BERT with
+これは、2 つの新しい技術を使用して BERT モデルと RoBERTa モデルを改善します。 1つ目は、
+もつれを解く注意メカニズム。各単語は、その内容をエンコードする 2 つのベクトルを使用して表現され、
+単語間の注意の重みは、それらの単語のもつれ解除行列を使用して計算されます。
+内容と相対的な位置。 2 番目に、強化されたマスク デコーダを使用して、出力ソフトマックス レイヤを次のように置き換えます。
+モデルの事前トレーニング用にマスクされたトークンを予測します。これら 2 つの手法により効率が大幅に向上することを示します。
+モデルの事前トレーニングと下流タスクのパフォーマンスの向上。 RoBERTa-Large と比較すると、DeBERTa モデルは半分のレベルでトレーニングされています。
+トレーニング データは幅広い NLP タスクで一貫して優れたパフォーマンスを示し、MNLI で +0.9% の改善を達成しました。
+(90.2% 対 91.1%)、SQuAD v2.0 では +2.3% (88.4% 対 90.7%)、RACE では +3.6% (83.2% 対 86.8%) でした。 DeBERTa コードと
+事前トレーニングされたモデルは https://github.com/microsoft/DeBERTa で公開されます。*
+
+
+このモデルは [DeBERTa](https://huggingface.co/DeBERTa) によって寄稿されました。このモデルの TF 2.0 実装は、
+[kamalkraj](https://huggingface.co/kamalkraj) による寄稿。元のコードは [こちら](https://github.com/microsoft/DeBERTa) にあります。
+
+## Resources
+
+DeBERTa を使い始めるのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示される) リソースのリスト。ここに含めるリソースの送信に興味がある場合は、お気軽にプル リクエストを開いてください。審査させていただきます。リソースは、既存のリソースを複製するのではなく、何か新しいものを示すことが理想的です。
+
+
+
+
+## DebertaModel
+
+[[autodoc]] DebertaModel
+ - forward
+
+## DebertaPreTrainedModel
+
+[[autodoc]] DebertaPreTrainedModel
+
+## DebertaForMaskedLM
+
+[[autodoc]] DebertaForMaskedLM
+ - forward
+
+## DebertaForSequenceClassification
+
+[[autodoc]] DebertaForSequenceClassification
+ - forward
+
+## DebertaForTokenClassification
+
+[[autodoc]] DebertaForTokenClassification
+ - forward
+
+## DebertaForQuestionAnswering
+
+[[autodoc]] DebertaForQuestionAnswering
+ - forward
+
+
+
+
+## TFDebertaModel
+
+[[autodoc]] TFDebertaModel
+ - call
+
+## TFDebertaPreTrainedModel
+
+[[autodoc]] TFDebertaPreTrainedModel
+ - call
+
+## TFDebertaForMaskedLM
+
+[[autodoc]] TFDebertaForMaskedLM
+ - call
+
+## TFDebertaForSequenceClassification
+
+[[autodoc]] TFDebertaForSequenceClassification
+ - call
+
+## TFDebertaForTokenClassification
+
+[[autodoc]] TFDebertaForTokenClassification
+ - call
+
+## TFDebertaForQuestionAnswering
+
+[[autodoc]] TFDebertaForQuestionAnswering
+ - call
+
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/decision_transformer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/decision_transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..9c7f27bbeeec2d1718838fb314a166960fa41ab1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/decision_transformer.md
@@ -0,0 +1,53 @@
+
+
+# Decision Transformer
+
+## Overview
+
+Decision Transformer モデルは、[Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) で提案されました。
+Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+
+論文の要約は次のとおりです。
+
+*強化学習(RL)をシーケンスモデリング問題として抽象化するフレームワークを紹介します。
+これにより、Transformer アーキテクチャのシンプルさとスケーラビリティ、および関連する進歩を活用できるようになります。
+ GPT-x や BERT などの言語モデリングで。特に、Decision Transformer というアーキテクチャを紹介します。
+ RL の問題を条件付きシーケンス モデリングとして投げかけます。値関数に適合する以前の RL アプローチとは異なり、
+ ポリシー勾配を計算すると、Decision Transformer は因果的にマスクされたアルゴリズムを利用して最適なアクションを出力するだけです。
+ 変成器。望ましいリターン (報酬)、過去の状態、アクションに基づいて自己回帰モデルを条件付けすることにより、
+ Decision Transformer モデルは、望ましいリターンを達成する将来のアクションを生成できます。そのシンプルさにも関わらず、
+ Decision Transformer は、最先端のモデルフリーのオフライン RL ベースラインのパフォーマンスと同等、またはそれを超えています。
+ Atari、OpenAI Gym、Key-to-Door タスク*
+
+このバージョンのモデルは、状態がベクトルであるタスク用です。
+
+このモデルは、[edbeeching](https://huggingface.co/edbeeching) によって提供されました。元のコードは [ここ](https://github.com/kzl/decion-transformer) にあります。
+
+## DecisionTransformerConfig
+
+[[autodoc]] DecisionTransformerConfig
+
+
+## DecisionTransformerGPT2Model
+
+[[autodoc]] DecisionTransformerGPT2Model
+ - forward
+
+## DecisionTransformerModel
+
+[[autodoc]] DecisionTransformerModel
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deformable_detr.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deformable_detr.md
new file mode 100644
index 0000000000000000000000000000000000000000..ccb6ec42f869b64faa4cff10e102531fc622ca69
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deformable_detr.md
@@ -0,0 +1,75 @@
+
+
+# Deformable DETR
+
+## Overview
+
+変形可能 DETR モデルは、Xizhou Zhu、Weijie Su、Lewei Lu、Bin Li、Xiaogang Wang, Jifeng Dai によって [Deformable DETR: Deformable Transformers for End-to-End Object Detection](https://arxiv.org/abs/2010.04159) で提案されました
+変形可能な DETR は、参照周囲の少数の主要なサンプリング ポイントのみに注目する新しい変形可能なアテンション モジュールを利用することにより、収束の遅さの問題と元の [DETR](detr) の制限された特徴の空間解像度を軽減します。
+
+論文の要約は次のとおりです。
+
+*DETR は、優れたパフォーマンスを実証しながら、物体検出における多くの手作業で設計されたコンポーネントの必要性を排除するために最近提案されました。ただし、画像特徴マップの処理における Transformer アテンション モジュールの制限により、収束が遅く、特徴の空間解像度が制限されるという問題があります。これらの問題を軽減するために、私たちは Deformable DETR を提案しました。この DETR のアテンション モジュールは、参照周囲の少数の主要なサンプリング ポイントのみに注目します。変形可能な DETR は、10 分の 1 のトレーニング エポックで、DETR よりも優れたパフォーマンス (特に小さなオブジェクトの場合) を達成できます。 COCO ベンチマークに関する広範な実験により、私たちのアプローチの有効性が実証されました。*
+
+ 変形可能な DETR アーキテクチャ。 元の論文 から抜粋。
+
+このモデルは、[nielsr](https://huggingface.co/nielsr) によって提供されました。元のコードは [ここ](https://github.com/fundamentalvision/Deformable-DETR) にあります。
+
+## Usage tips
+
+
+ - トレーニング Deformable DETR は、元の [DETR](detr) モデルをトレーニングすることと同等です。デモ ノートブックについては、以下の [resources](#resources) セクションを参照してください。
+
+## Resources
+
+Deformable DETR の使用を開始するのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示される) リソースのリスト。
+
+
+
+
+## DeiTModel
+
+[[autodoc]] DeiTModel
+ - forward
+
+## DeiTForMaskedImageModeling
+
+[[autodoc]] DeiTForMaskedImageModeling
+ - forward
+
+## DeiTForImageClassification
+
+[[autodoc]] DeiTForImageClassification
+ - forward
+
+## DeiTForImageClassificationWithTeacher
+
+[[autodoc]] DeiTForImageClassificationWithTeacher
+ - forward
+
+
+
+
+## TFDeiTModel
+
+[[autodoc]] TFDeiTModel
+ - call
+
+## TFDeiTForMaskedImageModeling
+
+[[autodoc]] TFDeiTForMaskedImageModeling
+ - call
+
+## TFDeiTForImageClassification
+
+[[autodoc]] TFDeiTForImageClassification
+ - call
+
+## TFDeiTForImageClassificationWithTeacher
+
+[[autodoc]] TFDeiTForImageClassificationWithTeacher
+ - call
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deplot.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deplot.md
new file mode 100644
index 0000000000000000000000000000000000000000..26871d1e7dde664126c4d857a9c29bf4f521a75a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deplot.md
@@ -0,0 +1,65 @@
+
+
+# DePlot
+
+## Overview
+
+DePlot は、Fangyu Liu、Julian Martin Aisenschlos、Francesco Piccinno、Syrine Krichene、Chenxi Pang, Kenton Lee, Mandar Joshi, Wenhu Chen, Nigel Collier, Yasemin Altun. の論文 [DePlot: One-shot visual language reasoning by plot-to-table translation](https://arxiv.org/abs/2212.10505) で提案されました。パン・
+
+論文の要約には次のように記載されています。
+
+*チャートやプロットなどの視覚言語は人間の世界に遍在しています。プロットやチャートを理解するには、強力な推論スキルが必要です。従来の最先端 (SOTA) モデルには少なくとも数万のトレーニング サンプルが必要であり、その推論能力は、特に人間が作成した複雑なクエリでは依然として大幅に制限されています。この論文では、視覚言語推論に対する最初のワンショット ソリューションを紹介します。私たちは、視覚言語推論の課題を 2 つのステップに分解します。(1) プロットからテキストへの翻訳と、(2) 翻訳されたテキストに対する推論です。この方法の鍵となるのは、プロットまたはチャートの画像を線形化されたテーブルに変換する、DePlot という名前のモダリティ変換モジュールです。その後、DePlot の出力を直接使用して、事前トレーニング済みの大規模言語モデル (LLM) をプロンプトし、LLM の少数ショット推論機能を利用できます。 DePlot を取得するには、統一されたタスク形式とメトリクスを確立することでプロットからテーブルへのタスクを標準化し、このタスクで DePlot をエンドツーエンドでトレーニングします。 DePlot は、プラグアンドプレイ方式で LLM とともに既製で使用できます。 28,000 を超えるデータ ポイントで微調整された SOTA モデルと比較して、ワンショット プロンプトのみを使用する DePlot+LLM は、チャート QA タスクからの人が作成したクエリに関して、微調整された SOTA より 24.0% の改善を達成しました。*
+
+DePlot は、`Pix2Struct` アーキテクチャを使用してトレーニングされたモデルです。 `Pix2Struct` の詳細については、[Pix2Struct ドキュメント](https://huggingface.co/docs/transformers/main/en/model_doc/pix2struct) を参照してください。
+DePlot は、`Pix2Struct` アーキテクチャの Visual Question Answering サブセットです。入力された質問を画像上にレンダリングし、答えを予測します。
+
+## Usage example
+
+現在、DePlot で使用できるチェックポイントは 1 つです。
+
+- `google/deplot`: ChartQA データセットで微調整された DePlot
+
+```python
+from transformers import AutoProcessor, Pix2StructForConditionalGeneration
+import requests
+from PIL import Image
+
+model = Pix2StructForConditionalGeneration.from_pretrained("google/deplot")
+processor = AutoProcessor.from_pretrained("google/deplot")
+url = "https://raw.githubusercontent.com/vis-nlp/ChartQA/main/ChartQA%20Dataset/val/png/5090.png"
+image = Image.open(requests.get(url, stream=True).raw)
+
+inputs = processor(images=image, text="Generate underlying data table of the figure below:", return_tensors="pt")
+predictions = model.generate(**inputs, max_new_tokens=512)
+print(processor.decode(predictions[0], skip_special_tokens=True))
+```
+
+## Fine-tuning
+
+DePlot を微調整するには、pix2struct [微調整ノートブック](https://github.com/huggingface/notebooks/blob/main/examples/image_captioning_pix2struct.ipynb) を参照してください。 `Pix2Struct` モデルの場合、Adafactor とコサイン学習率スケジューラを使用してモデルを微調整すると、収束が高速化されることがわかりました。
+```python
+from transformers.optimization import Adafactor, get_cosine_schedule_with_warmup
+
+optimizer = Adafactor(self.parameters(), scale_parameter=False, relative_step=False, lr=0.01, weight_decay=1e-05)
+scheduler = get_cosine_schedule_with_warmup(optimizer, num_warmup_steps=1000, num_training_steps=40000)
+```
+
+
+
+DePlot は、`Pix2Struct`アーキテクチャを使用してトレーニングされたモデルです。 API リファレンスについては、[`Pix2Struct` ドキュメント](pix2struct) を参照してください。
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deta.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deta.md
new file mode 100644
index 0000000000000000000000000000000000000000..615f8396577fdb784c692972352736dcd5ef725f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/deta.md
@@ -0,0 +1,64 @@
+
+
+# DETA
+
+## Overview
+
+DETA モデルは、[NMS Strikes Back](https://arxiv.org/abs/2212.06137) で Jeffrey Ouyang-Zhang、Jang Hyun Cho、Xingyi Zhou、Philipp Krähenbühl によって提案されました。
+DETA (Detection Transformers with Assignment の略) は、1 対 1 の 2 部ハンガリアン マッチング損失を置き換えることにより、[Deformable DETR](deformable_detr) を改善します。
+非最大抑制 (NMS) を備えた従来の検出器で使用される 1 対多のラベル割り当てを使用します。これにより、最大 2.5 mAP の大幅な増加が得られます。
+
+論文の要約は次のとおりです。
+
+*Detection Transformer (DETR) は、トレーニング中に 1 対 1 の 2 部マッチングを使用してクエリを一意のオブジェクトに直接変換し、エンドツーエンドのオブジェクト検出を可能にします。最近、これらのモデルは、紛れもない優雅さで COCO の従来の検出器を上回りました。ただし、モデル アーキテクチャやトレーニング スケジュールなど、さまざまな設計において従来の検出器とは異なるため、1 対 1 マッチングの有効性は完全には理解されていません。この研究では、DETR での 1 対 1 のハンガリー語マッチングと、非最大監視 (NMS) を備えた従来の検出器での 1 対多のラベル割り当てとの間の厳密な比較を行います。驚くべきことに、NMS を使用した 1 対多の割り当ては、同じ設定の下で標準的な 1 対 1 のマッチングよりも一貫して優れており、最大 2.5 mAP という大幅な向上が見られます。従来の IoU ベースのラベル割り当てを使用して Deformable-DETR をトレーニングする当社の検出器は、ResNet50 バックボーンを使用して 12 エポック (1x スケジュール) 以内に 50.2 COCO mAP を達成し、この設定で既存のすべての従来の検出器またはトランスベースの検出器を上回りました。複数のデータセット、スケジュール、アーキテクチャに関して、私たちは一貫して、パフォーマンスの高い検出トランスフォーマーには二部マッチングが不要であることを示しています。さらに、検出トランスの成功は、表現力豊かなトランス アーキテクチャによるものであると考えています。*
+
+ DETA の概要。 元の論文 から抜粋。
+
+このモデルは、[nielsr](https://huggingface.co/nielsr) によって提供されました。
+元のコードは [ここ](https://github.com/jozhang97/DETA) にあります。
+
+## Resources
+
+DETA の使用を開始するのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示されている) リソースのリスト。
+
+- DETA のデモ ノートブックは [こちら](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/DETA) にあります。
+- 参照: [オブジェクト検出タスク ガイド](../tasks/object_detection)
+
+ここに含めるリソースの送信に興味がある場合は、お気軽にプル リクエストを開いてください。審査させていただきます。リソースは、既存のリソースを複製するのではなく、何か新しいものを示すことが理想的です。
+
+## DetaConfig
+
+[[autodoc]] DetaConfig
+
+## DetaImageProcessor
+
+[[autodoc]] DetaImageProcessor
+ - preprocess
+ - post_process_object_detection
+
+## DetaModel
+
+[[autodoc]] DetaModel
+ - forward
+
+## DetaForObjectDetection
+
+[[autodoc]] DetaForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/detr.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/detr.md
new file mode 100644
index 0000000000000000000000000000000000000000..3342b123a01b833795847c8b46c723ddb53f45f4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/detr.md
@@ -0,0 +1,226 @@
+
+
+# DETR
+
+## Overview
+
+DETR モデルは、[Transformers を使用したエンドツーエンドのオブジェクト検出](https://arxiv.org/abs/2005.12872) で提案されました。
+Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov and Sergey Zagoruyko ルイコ。 DETR
+畳み込みバックボーンと、その後にエンドツーエンドでトレーニングできるエンコーダー/デコーダー Transformer で構成されます。
+物体の検出。 Faster-R-CNN や Mask-R-CNN などのモデルの複雑さの多くが大幅に簡素化されます。
+領域提案、非最大抑制手順、アンカー生成などです。さらに、DETR は次のようにすることもできます。
+デコーダ出力の上にマスク ヘッドを追加するだけで、パノプティック セグメンテーションを実行できるように自然に拡張されています。
+
+論文の要約は次のとおりです。
+
+*物体検出を直接集合予測問題として見る新しい方法を紹介します。私たちのアプローチは、
+検出パイプラインにより、非最大抑制などの多くの手作業で設計されたコンポーネントの必要性が効果的に排除されます。
+タスクに関する事前の知識を明示的にエンコードするプロシージャまたはアンカーの生成。の主な成分は、
+DEtection TRansformer または DETR と呼ばれる新しいフレームワークは、セットベースのグローバル損失であり、
+二部マッチング、およびトランスフォーマー エンコーダー/デコーダー アーキテクチャ。学習されたオブジェクト クエリの固定された小さなセットが与えられると、
+DETR は、オブジェクトとグローバル イメージ コンテキストの関係について推論し、最終セットを直接出力します。
+並行して予想も。新しいモデルは概念的にシンプルであり、多くのモデルとは異なり、特殊なライブラリを必要としません。
+他の最新の検出器。 DETR は、確立された、および同等の精度と実行時のパフォーマンスを実証します。
+困難な COCO 物体検出データセットに基づく、高度に最適化された Faster RCNN ベースライン。さらに、DETR は簡単に実行できます。
+統一された方法でパノプティック セグメンテーションを生成するために一般化されました。競合他社を大幅に上回るパフォーマンスを示しています
+ベースライン*
+
+このモデルは、[nielsr](https://huggingface.co/nielsr) によって提供されました。元のコードは [こちら](https://github.com/facebookresearch/detr) にあります。
+
+## How DETR works
+
+[`~transformers.DetrForObjectDetection`] がどのように機能するかを説明する TLDR は次のとおりです。
+
+まず、事前にトレーニングされた畳み込みバックボーンを通じて画像が送信されます (論文では、著者らは次のように使用しています)。
+ResNet-50/ResNet-101)。バッチ ディメンションも追加すると仮定します。これは、バックボーンへの入力が
+画像に 3 つのカラー チャネル (RGB) があると仮定した場合の、形状 `(batch_size, 3, height, width)` のテンソル。 CNNのバックボーン
+通常は `(batch_size, 2048, height/32, width/32)` の形状の、新しい低解像度の特徴マップを出力します。これは
+次に、DETR の Transformer の隠れ次元 (デフォルトでは `256`) に一致するように投影されます。
+`nn.Conv2D` レイヤー。これで、形状 `(batch_size, 256, height/32, width/32)` のテンソルが完成しました。
+特徴マップは平坦化および転置され、形状 `(batch_size, seq_len, d_model)` のテンソルを取得します =
+`(batch_size, width/32*height/32, 256)`。したがって、NLP モデルとの違いは、シーケンスの長さが実際には
+通常よりも長くなりますが、「d_model」は小さくなります (NLP では通常 768 以上です)。
+
+次に、これがエンコーダを介して送信され、同じ形状の `encoder_hidden_states` が出力されます (次のように考えることができます)。
+これらは画像の特徴として)。次に、いわゆる **オブジェクト クエリ**がデコーダを通じて送信されます。これは形状のテンソルです
+`(batch_size, num_queries, d_model)`。通常、`num_queries` は 100 に設定され、ゼロで初期化されます。
+これらの入力埋め込みは学習された位置エンコーディングであり、作成者はこれをオブジェクト クエリと呼び、同様に
+エンコーダでは、それらは各アテンション層の入力に追加されます。各オブジェクト クエリは特定のオブジェクトを検索します。
+画像では。デコーダは、複数のセルフ アテンション レイヤとエンコーダ デコーダ アテンション レイヤを通じてこれらの埋め込みを更新します。
+同じ形状の `decoder_hidden_states` を出力します: `(batch_size, num_queries, d_model)`。次に頭が2つ
+オブジェクト検出のために上部に追加されます。各オブジェクト クエリをオブジェクトの 1 つに分類するための線形レイヤー、または「いいえ」
+オブジェクト」、および各クエリの境界ボックスを予測する MLP。
+
+モデルは **2 部マッチング損失**を使用してトレーニングされます。つまり、実際に行うことは、予測されたクラスを比較することです +
+グラウンド トゥルース アノテーションに対する N = 100 個の各オブジェクト クエリの境界ボックス (同じ長さ N までパディング)
+(したがって、画像にオブジェクトが 4 つしか含まれていない場合、96 個の注釈にはクラスとして「オブジェクトなし」、およびクラスとして「境界ボックスなし」が含まれるだけになります。
+境界ボックス)。 [Hungarian matching algorithm](https://en.wikipedia.org/wiki/Hungarian_algorithm) は、検索に使用されます。
+N 個のクエリのそれぞれから N 個の注釈のそれぞれへの最適な 1 対 1 のマッピング。次に、標準クロスエントロピー (
+クラス)、および L1 と [generalized IoU loss](https://giou.stanford.edu/) の線形結合 (
+境界ボックス) は、モデルのパラメーターを最適化するために使用されます。
+
+DETR は、パノプティック セグメンテーション (セマンティック セグメンテーションとインスタンスを統合する) を実行するように自然に拡張できます。
+セグメンテーション)。 [`~transformers.DetrForSegmentation`] はセグメンテーション マスク ヘッドを上に追加します
+[`~transformers.DetrForObjectDetection`]。マスク ヘッドは、共同でトレーニングすることも、2 段階のプロセスでトレーニングすることもできます。
+ここで、最初に [`~transformers.DetrForObjectDetection`] モデルをトレーニングして、両方の周囲の境界ボックスを検出します。
+「もの」(インスタンス)と「もの」(木、道路、空などの背景のもの)をすべて凍結し、すべての重みをフリーズしてのみトレーニングします。
+25 エポックのマスクヘッド。実験的には、これら 2 つのアプローチは同様の結果をもたらします。ボックスの予測は
+ハンガリー語のマッチングはボックス間の距離を使用して計算されるため、トレーニングを可能にするためにはこれが必要です。
+
+## Usage tips
+
+- DETR は、いわゆる **オブジェクト クエリ** を使用して、画像内のオブジェクトを検出します。クエリの数によって最大値が決まります
+ 単一の画像内で検出できるオブジェクトの数。デフォルトでは 100 に設定されます (パラメーターを参照)
+ [`~transformers.DetrConfig`] の `num_queries`)。ある程度の余裕があるのは良いことです (COCO では、
+ 著者は 100 を使用しましたが、COCO イメージ内のオブジェクトの最大数は約 70 です)。
+- DETR のデコーダーは、クエリの埋め込みを並行して更新します。これは GPT-2 のような言語モデルとは異なります。
+ 並列ではなく自己回帰デコードを使用します。したがって、因果的注意マスクは使用されません。
+- DETR は、投影前に各セルフアテンション層とクロスアテンション層の隠れ状態に位置埋め込みを追加します。
+ クエリとキーに。画像の位置埋め込みについては、固定正弦波または学習済みのどちらかを選択できます。
+ 絶対位置埋め込み。デフォルトでは、パラメータ `position_embedding_type` は
+ [`~transformers.DetrConfig`] は `"sine"` に設定されます。
+- DETR の作成者は、トレーニング中に、特にデコーダで補助損失を使用すると役立つことに気づきました。
+ モデルは各クラスの正しい数のオブジェクトを出力します。パラメータ `auxiliary_loss` を設定すると、
+ [`~transformers.DetrConfig`] を`True`に設定し、フィードフォワード ニューラル ネットワークとハンガリー損失を予測します
+ は各デコーダ層の後に追加されます (FFN がパラメータを共有する)。
+- 複数のノードにわたる分散環境でモデルをトレーニングする場合は、
+ _modeling_detr.py_ の _DetrLoss_ クラスの _num_boxes_ 変数。複数のノードでトレーニングする場合、これは次のようにする必要があります
+ 元の実装で見られるように、すべてのノードにわたるターゲット ボックスの平均数に設定されます [こちら](https://github.com/facebookresearch/detr/blob/a54b77800eb8e64e3ad0d8237789fcbf2f8350c5/models/detr.py#L227-L232) 。
+- [`~transformers.DetrForObjectDetection`] および [`~transformers.DetrForSegmentation`] は次のように初期化できます。
+ [timm ライブラリ](https://github.com/rwightman/pytorch-image-models) で利用可能な畳み込みバックボーン。
+ たとえば、MobileNet バックボーンを使用した初期化は、次の `backbone` 属性を設定することで実行できます。
+ [`~transformers.DetrConfig`] を `"tf_mobilenetv3_small_075"` に設定し、それを使用してモデルを初期化します。
+ 構成。
+- DETR は、最短辺が一定のピクセル数以上になり、最長辺が一定量以上になるように入力画像のサイズを変更します。
+ 最大 1333 ピクセル。トレーニング時に、最短辺がランダムに に設定されるようにスケール拡張が使用されます。
+ 最小 480、最大 800 ピクセル。推論時には、最短辺が 800 に設定されます。
+
+使用できます
+ [`~transformers.DetrImageProcessor`] 用の画像 (およびオプションの COCO 形式の注釈) を準備します。
+ モデル。このサイズ変更により、バッチ内の画像のサイズが異なる場合があります。 DETR は、画像を最大までパディングすることでこの問題を解決します。
+ どのピクセルが実数でどのピクセルがパディングであるかを示すピクセル マスクを作成することによって、バッチ内の最大サイズを決定します。
+ あるいは、画像をバッチ処理するためにカスタムの `collate_fn` を定義することもできます。
+ [`~transformers.DetrImageProcessor.pad_and_create_pixel_mask`]。
+- 画像のサイズによって使用されるメモリの量が決まり、したがって「batch_size」も決まります。
+ GPU あたり 2 のバッチ サイズを使用することをお勧めします。詳細については、[この Github スレッド](https://github.com/facebookresearch/detr/issues/150) を参照してください。
+
+DETR モデルをインスタンス化するには 3 つの方法があります (好みに応じて)。
+
+オプション 1: モデル全体の事前トレーニングされた重みを使用して DETR をインスタンス化する
+
+```py
+>>> from transformers import DetrForObjectDetection
+
+>>> model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
+```
+
+オプション 2: Transformer についてはランダムに初期化された重みを使用して DETR をインスタンス化しますが、バックボーンについては事前にトレーニングされた重みを使用します
+
+```py
+>>> from transformers import DetrConfig, DetrForObjectDetection
+
+>>> config = DetrConfig()
+>>> model = DetrForObjectDetection(config)
+```
+
+オプション 3: バックボーン + トランスフォーマーのランダムに初期化された重みを使用して DETR をインスタンス化します。
+
+```py
+>>> config = DetrConfig(use_pretrained_backbone=False)
+>>> model = DetrForObjectDetection(config)
+```
+
+| Task | Object detection | Instance segmentation | Panoptic segmentation |
+|------|------------------|-----------------------|-----------------------|
+| **Description** |画像内のオブジェクトの周囲の境界ボックスとクラス ラベルを予測する | 画像内のオブジェクト (つまりインスタンス) の周囲のマスクを予測する | 画像内のオブジェクト (インスタンス) と「もの」 (木や道路などの背景) の両方の周囲のマスクを予測します |
+| **Model** | [`~transformers.DetrForObjectDetection`] | [`~transformers.DetrForSegmentation`] | [`~transformers.DetrForSegmentation`] |
+| **Example dataset** | COCO detection | COCO detection, COCO panoptic | COCO panoptic | |
+| **Format of annotations to provide to** [`~transformers.DetrImageProcessor`] | {'image_id': `int`, 'annotations': `List[Dict]`} each Dict being a COCO object annotation | {'image_id': `int`, 'annotations': `List[Dict]`} (in case of COCO detection) or {'file_name': `str`, 'image_id': `int`, 'segments_info': `List[Dict]`} (in case of COCO panoptic) | {'file_name': `str`, 'image_id': `int`, 'segments_info': `List[Dict]`} and masks_path (path to directory containing PNG files of the masks) |
+| **Postprocessing** (i.e. converting the output of the model to Pascal VOC format) | [`~transformers.DetrImageProcessor.post_process`] | [`~transformers.DetrImageProcessor.post_process_segmentation`] | [`~transformers.DetrImageProcessor.post_process_segmentation`], [`~transformers.DetrImageProcessor.post_process_panoptic`] |
+| **evaluators** | `CocoEvaluator` with `iou_types="bbox"` | `CocoEvaluator` with `iou_types="bbox"` or `"segm"` | `CocoEvaluator` with `iou_tupes="bbox"` or `"segm"`, `PanopticEvaluator` |
+
+つまり、COCO 検出または COCO パノプティック形式でデータを準備してから、次を使用する必要があります。
+[`~transformers.DetrImageProcessor`] `pixel_values`、`pixel_mask`、およびオプションを作成します。
+「ラベル」。これを使用してモデルをトレーニング (または微調整) できます。評価するには、まず、
+[`~transformers.DetrImageProcessor`] の後処理メソッドの 1 つを使用したモデルの出力。これらはできます
+`CocoEvaluator` または `PanopticEvaluator` のいずれかに提供され、次のようなメトリクスを計算できます。
+平均平均精度 (mAP) とパノラマ品質 (PQ)。後者のオブジェクトは [元のリポジトリ](https://github.com/facebookresearch/detr) に実装されています。評価の詳細については、[サンプル ノートブック](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/DETR) を参照してください。
+
+## Resources
+
+DETR の使用を開始するのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示されている) リソースのリスト。
+
+
+
+DialoGPT のアーキテクチャは GPT2 モデルに基づいています。API リファレンスと例については、[GPT2 のドキュメント ページ](openai-community/gpt2) を参照してください。
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/dinat.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/dinat.md
new file mode 100644
index 0000000000000000000000000000000000000000..a59b073d4669ef039467d84139a0c98032d71d63
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_doc/dinat.md
@@ -0,0 +1,93 @@
+
+
+# Dilated Neighborhood Attention Transformer
+
+## Overview
+
+DiNAT は [Dilated Neighborhood Attender Transformer](https://arxiv.org/abs/2209.15001) で提案されました。
+Ali Hassani and Humphrey Shi.
+
+[NAT](nat) を拡張するために、拡張近隣アテンション パターンを追加してグローバル コンテキストをキャプチャします。
+そしてそれと比較して大幅なパフォーマンスの向上が見られます。
+
+論文の要約は次のとおりです。
+
+*トランスフォーマーは急速に、さまざまなモダリティにわたって最も頻繁に適用される深層学習アーキテクチャの 1 つになりつつあります。
+ドメインとタスク。ビジョンでは、単純なトランスフォーマーへの継続的な取り組みに加えて、階層型トランスフォーマーが
+また、そのパフォーマンスと既存のフレームワークへの簡単な統合のおかげで、大きな注目を集めました。
+これらのモデルは通常、スライディング ウィンドウの近隣アテンション (NA) などの局所的な注意メカニズムを採用しています。
+または Swin Transformer のシフト ウィンドウ セルフ アテンション。自己注意の二次複雑さを軽減するのに効果的ですが、
+局所的な注意は、自己注意の最も望ましい 2 つの特性を弱めます。それは、長距離の相互依存性モデリングです。
+そして全体的な受容野。このペーパーでは、自然で柔軟で、
+NA への効率的な拡張により、よりグローバルなコンテキストを捕捉し、受容野をゼロから指数関数的に拡張することができます。
+追加費用。 NA のローカルな注目と DiNA のまばらなグローバルな注目は相互に補完し合うため、私たちは
+両方に基づいて構築された新しい階層型ビジョン トランスフォーマーである Dilated Neighborhood Attendant Transformer (DiNAT) を導入します。
+DiNAT のバリアントは、NAT、Swin、ConvNeXt などの強力なベースラインに比べて大幅に改善されています。
+私たちの大規模モデルは、COCO オブジェクト検出において Swin モデルよりも高速で、ボックス AP が 1.5% 優れています。
+COCO インスタンス セグメンテーションでは 1.3% のマスク AP、ADE20K セマンティック セグメンテーションでは 1.1% の mIoU。
+新しいフレームワークと組み合わせた当社の大規模バリアントは、COCO (58.2 PQ) 上の新しい最先端のパノプティック セグメンテーション モデルです。
+および ADE20K (48.5 PQ)、および Cityscapes (44.5 AP) および ADE20K (35.4 AP) のインスタンス セグメンテーション モデル (追加データなし)。
+また、ADE20K (58.2 mIoU) 上の最先端の特殊なセマンティック セグメンテーション モデルとも一致します。
+都市景観 (84.5 mIoU) では 2 位にランクされています (追加データなし)。 *
+
+
+ 異なる拡張値を使用した近隣アテンション。
+元の論文 から抜粋。
+
+このモデルは [Ali Hassani](https://huggingface.co/alihassanijr) によって提供されました。
+元のコードは [ここ](https://github.com/SHI-Labs/Neighborhood-Attendance-Transformer) にあります。
+
+## Usage tips
+
+DiNAT は *バックボーン* として使用できます。 「output_hidden_states = True」の場合、
+`hidden_states` と `reshaped_hidden_states` の両方を出力します。 `reshape_hidden_states` は、`(batch_size, height, width, num_channels)` ではなく、`(batch, num_channels, height, width)` の形状を持っています。
+
+ノート:
+- DiNAT は、[NATTEN](https://github.com/SHI-Labs/NATTEN/) による近隣アテンションと拡張近隣アテンションの実装に依存しています。
+[shi-labs.com/natten](https://shi-labs.com/natten) を参照して、Linux 用のビルド済みホイールを使用してインストールするか、`pip install natten` を実行してシステム上に構築できます。
+後者はコンパイルに時間がかかる可能性があることに注意してください。 NATTEN はまだ Windows デバイスをサポートしていません。
+- 現時点ではパッチ サイズ 4 のみがサポートされています。
+
+## Resources
+
+DiNAT の使用を開始するのに役立つ公式 Hugging Face およびコミュニティ (🌎 で示されている) リソースのリスト。
+
+
+
+複数の実験を実行する予定がある場合、実験間でメモリを適切にクリアするために、実験の間に Python カーネルを再起動してください。
+
+
+
+## Memory utilization at vanilla training
+
+[`Trainer`] を使用して、GPU パフォーマンスの最適化テクニックを使用せずにバッチサイズ 4 でモデルをトレーニングしましょう:
+
+
+```py
+>>> from transformers import TrainingArguments, Trainer, logging
+
+>>> logging.set_verbosity_error()
+
+
+>>> training_args = TrainingArguments(per_device_train_batch_size=4, **default_args)
+>>> trainer = Trainer(model=model, args=training_args, train_dataset=ds)
+>>> result = trainer.train()
+>>> print_summary(result)
+```
+
+```
+Time: 57.82
+Samples/second: 8.86
+GPU memory occupied: 14949 MB.
+```
+
+既に、比較的小さいバッチサイズでも、GPUのほとんどのメモリがすでに使用されていることがわかります。しかし、より大きなバッチサイズを使用することは、しばしばモデルの収束が速くなったり、最終的な性能が向上したりすることがあります。したがって、理想的には、バッチサイズをモデルの要件に合わせて調整したいのですが、GPUの制限に合わせて調整する必要はありません。興味深いことに、モデルのサイズよりもはるかに多くのメモリを使用しています。なぜそうなるのかを少し理解するために、モデルの操作とメモリの必要性を見てみましょう。
+
+
+## Anatomy of Model's Operations
+
+Transformerアーキテクチャには、計算強度によって以下の3つの主要な操作グループが含まれています。
+
+1. **テンソルの収縮**
+
+ 線形層とMulti-Head Attentionのコンポーネントは、すべてバッチ処理された **行列-行列の乗算** を行います。これらの操作は、Transformerのトレーニングにおいて最も計算集約的な部分です。
+
+2. **統計的正規化**
+
+ Softmaxと層正規化は、テンソルの収縮よりも計算負荷が少なく、1つまたは複数の **縮約操作** を含み、その結果がマップを介して適用されます。
+
+3. **要素ごとの演算子**
+
+ これらは残りの演算子です:**バイアス、ドロップアウト、活性化、および残差接続** です。これらは最も計算集約的な操作ではありません。
+
+パフォーマンスのボトルネックを分析する際に、この知識は役立つことがあります。
+
+この要約は、[Data Movement Is All You Need: Optimizing Transformers 2020に関するケーススタディ](https://arxiv.org/abs/2007.00072)から派生しています。
+
+## Anatomy of Model's Memory
+
+モデルのトレーニングがGPUに配置されたモデルよりもはるかに多くのメモリを使用することを見てきました。これは、トレーニング中にGPUメモリを使用する多くのコンポーネントが存在するためです。GPUメモリ上のコンポーネントは以下の通りです:
+
+1. モデルの重み
+2. オプティマイザの状態
+3. 勾配
+4. 勾配計算のために保存された前向き活性化
+5. 一時バッファ
+6. 機能固有のメモリ
+
+通常、AdamWを使用して混合精度でトレーニングされたモデルは、モデルパラメータごとに18バイトとアクティベーションメモリが必要です。推論ではオプティマイザの状態と勾配は不要ですので、これらを差し引くことができます。したがって、混合精度の推論においては、モデルパラメータごとに6バイトとアクティベーションメモリが必要です。
+
+詳細を見てみましょう。
+
+
+**モデルの重み:**
+
+- fp32トレーニングのパラメーター数 * 4バイト
+- ミックスプレシジョントレーニングのパラメーター数 * 6バイト(メモリ内にfp32とfp16のモデルを維持)
+
+**オプティマイザの状態:**
+
+- 通常のAdamWのパラメーター数 * 8バイト(2つの状態を維持)
+- 8-bit AdamWオプティマイザのパラメーター数 * 2バイト([bitsandbytes](https://github.com/TimDettmers/bitsandbytes)のようなオプティマイザ)
+- モーメンタムを持つSGDのようなオプティマイザのパラメーター数 * 4バイト(1つの状態を維持)
+
+**勾配**
+
+- fp32またはミックスプレシジョントレーニングのパラメーター数 * 4バイト(勾配は常にfp32で保持)
+
+**フォワードアクティベーション**
+
+- サイズは多くの要因に依存し、主要な要因はシーケンスの長さ、隠れ層のサイズ、およびバッチサイズです。
+
+フォワードとバックワードの関数によって渡され、返される入力と出力、および勾配計算のために保存されるフォワードアクティベーションがあります。
+
+**一時的なメモリ**
+
+さらに、計算が完了した後に解放されるさまざまな一時変数がありますが、これらは一時的に追加のメモリを必要とし、OOMに達する可能性があります。したがって、コーディング時にはこのような一時変数に戦略的に考え、必要なくなったら明示的に解放することが非常に重要です。
+
+**機能固有のメモリ**
+
+次に、ソフトウェアには特別なメモリ要件がある場合があります。たとえば、ビームサーチを使用してテキストを生成する場合、ソフトウェアは複数の入力と出力のコピーを維持する必要があります。
+
+**`forward`と`backward`の実行速度**
+
+畳み込み層と線形層では、バックワードにフォワードと比べて2倍のFLOPSがあり、一般的には約2倍遅くなります(バックワードのサイズが不便であることがあるため、それ以上になることがあります)。 アクティベーションは通常、バンド幅制限されており、バックワードでアクティベーションがフォワードよりも多くのデータを読むことが一般的です(たとえば、アクティベーションフォワードは1回読み取り、1回書き込み、アクティベーションバックワードはフォワードのgradOutputおよび出力を2回読み取り、1回書き込みます)。
+
+ご覧の通り、GPUメモリを節約したり操作を高速化できる可能性のあるいくつかの場所があります。 GPUの利用と計算速度に影響を与える要因を理解したので、パフォーマンス最適化の技術については、[単一GPUでの効率的なトレーニングのための方法とツール](perf_train_gpu_one)のドキュメンテーションページを参照してください。
+
+詳細を見てみましょう。
+
+
+
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_sharing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_sharing.md
new file mode 100644
index 0000000000000000000000000000000000000000..16d47057052b95bf26eadcac6affea90fb7d0808
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_sharing.md
@@ -0,0 +1,262 @@
+
+
+# Share a Model
+
+最後の2つのチュートリアルでは、PyTorch、Keras、および🤗 Accelerateを使用してモデルをファインチューニングする方法を示しました。次のステップは、モデルをコミュニティと共有することです!Hugging Faceでは、知識とリソースを公開的に共有し、人工知能を誰にでも提供することを信じています。他の人々が時間とリソースを節約できるように、モデルをコミュニティと共有することを検討することをお勧めします。
+
+このチュートリアルでは、訓練済みまたはファインチューニングされたモデルを[Model Hub](https://huggingface.co/models)に共有する2つの方法を学びます:
+
+- プログラムでファイルをHubにプッシュする。
+- ウェブインターフェースを使用してファイルをHubにドラッグアンドドロップする。
+
+VIDEO
+
+
+
+コミュニティとモデルを共有するには、[huggingface.co](https://huggingface.co/join)でアカウントが必要です。既存の組織に参加したり、新しい組織を作成したりすることもできます。
+
+
+
+## Repository Features
+
+Model Hub上の各リポジトリは、通常のGitHubリポジトリのように動作します。リポジトリはバージョニング、コミット履歴、違いの視覚化の機能を提供します。
+
+Model Hubの組み込みバージョニングはgitおよび[git-lfs](https://git-lfs.github.com/)に基づいています。言い換えれば、モデルを1つのリポジトリとして扱うことができ、より大きなアクセス制御とスケーラビリティを実現します。バージョン管理には*リビジョン*があり、コミットハッシュ、タグ、またはブランチ名で特定のモデルバージョンをピン留めする方法です。
+
+その結果、`revision`パラメータを使用して特定のモデルバージョンをロードできます:
+
+```py
+>>> model = AutoModel.from_pretrained(
+... "julien-c/EsperBERTo-small", revision="4c77982" # タグ名、またはブランチ名、またはコミットハッシュ
+... )
+```
+
+ファイルはリポジトリ内で簡単に編集でき、コミット履歴と差分を表示できます:
+
+
+
+## Set Up
+
+モデルをHubに共有する前に、Hugging Faceの認証情報が必要です。ターミナルへのアクセス権がある場合、🤗 Transformersがインストールされている仮想環境で以下のコマンドを実行します。これにより、アクセストークンがHugging Faceのキャッシュフォルダに保存されます(デフォルトでは `~/.cache/` に保存されます):
+
+```bash
+huggingface-cli login
+```
+
+JupyterやColaboratoryのようなノートブックを使用している場合、[`huggingface_hub`](https://huggingface.co/docs/hub/adding-a-library)ライブラリがインストールされていることを確認してください。
+このライブラリを使用すると、Hubとプログラム的に対話できます。
+
+```bash
+pip install huggingface_hub
+```
+
+次に、`notebook_login`を使用してHubにサインインし、[こちらのリンク](https://huggingface.co/settings/token)にアクセスしてログインに使用するトークンを生成します:
+
+```python
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Convert a Model for all frameworks
+
+異なるフレームワークで作業している他のユーザーがあなたのモデルを使用できるようにするために、
+PyTorchおよびTensorFlowのチェックポイントでモデルを変換してアップロードすることをお勧めします。
+このステップをスキップすると、ユーザーは異なるフレームワークからモデルをロードできますが、
+モデルをオンザフライで変換する必要があるため、遅くなります。
+
+別のフレームワーク用にチェックポイントを変換することは簡単です。
+PyTorchとTensorFlowがインストールされていることを確認してください(インストール手順については[こちら](installation)を参照)し、
+その後、他のフレームワーク向けに特定のタスク用のモデルを見つけます。
+
+
+
+TensorFlowからPyTorchにチェックポイントを変換するには、`from_tf=True`を指定します:
+
+```python
+>>> pt_model = DistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_tf=True)
+>>> pt_model.save_pretrained("path/to/awesome-name-you-picked")
+```
+
+
+
+指定して、PyTorchからTensorFlowにチェックポイントを変換するには `from_pt=True` を使用します:
+
+```python
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_pt=True)
+```
+
+新しいTensorFlowモデルとその新しいチェックポイントを保存できます:
+
+```python
+>>> tf_model.save_pretrained("path/to/awesome-name-you-picked")
+```
+
+
+
+Flaxでモデルが利用可能な場合、PyTorchからFlaxへのチェックポイントの変換も行うことができます:
+
+```py
+>>> flax_model = FlaxDistilBertForSequenceClassification.from_pretrained(
+... "path/to/awesome-name-you-picked", from_pt=True
+... )
+```
+
+
+
+## Push a model during traning
+
+
+
+
+
+
+[`PushToHubCallback`]を使用してモデルをHubに共有します。[`PushToHubCallback`]関数には、次のものを追加します:
+
+- モデルの出力ディレクトリ。
+- トークナイザ。
+- `hub_model_id`、つまりHubのユーザー名とモデル名。
+
+```python
+>>> from transformers import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="./your_model_save_path", tokenizer=tokenizer, hub_model_id="your-username/my-awesome-model"
+... )
+```
+
+🤗 Transformersは[`fit`](https://keras.io/api/models/model_training_apis/)にコールバックを追加し、トレーニング済みモデルをHubにプッシュします:
+
+```py
+>>> model.fit(tf_train_dataset, validation_data=tf_validation_dataset, epochs=3, callbacks=push_to_hub_callback)
+```
+
+
+
+## `push_to_hub` 関数を使用する
+
+また、モデルを直接Hubにアップロードするために、`push_to_hub` を呼び出すこともできます。
+
+`push_to_hub` でモデル名を指定します:
+
+```py
+>>> pt_model.push_to_hub("my-awesome-model")
+```
+
+これにより、ユーザー名の下にモデル名 `my-awesome-model` を持つリポジトリが作成されます。
+ユーザーは、`from_pretrained` 関数を使用してモデルをロードできます:
+
+```py
+>>> from transformers import AutoModel
+
+>>> model = AutoModel.from_pretrained("your_username/my-awesome-model")
+```
+
+組織に所属し、モデルを組織名のもとにプッシュしたい場合、`repo_id` にそれを追加してください:
+
+```python
+>>> pt_model.push_to_hub("my-awesome-org/my-awesome-model")
+```
+
+`push_to_hub`関数は、モデルリポジトリに他のファイルを追加するためにも使用できます。例えば、トークナイザをモデルリポジトリに追加します:
+
+```py
+>>> tokenizer.push_to_hub("my-awesome-model")
+```
+
+あるいは、ファインチューニングされたPyTorchモデルのTensorFlowバージョンを追加したいかもしれません:
+
+```python
+>>> tf_model.push_to_hub("my-awesome-model")
+```
+
+Hugging Faceプロフィールに移動すると、新しく作成したモデルリポジトリが表示されるはずです。**Files**タブをクリックすると、リポジトリにアップロードしたすべてのファイルが表示されます。
+
+リポジトリにファイルを作成およびアップロードする方法の詳細については、Hubドキュメンテーション[こちら](https://huggingface.co/docs/hub/how-to-upstream)を参照してください。
+
+## Upload with the web interface
+
+コードを書かずにモデルをアップロードしたいユーザーは、Hubのウェブインターフェースを使用してモデルをアップロードできます。[huggingface.co/new](https://huggingface.co/new)を訪れて新しいリポジトリを作成します:
+
+
+
+ここから、モデルに関するいくつかの情報を追加します:
+
+- リポジトリの**所有者**を選択します。これはあなた自身または所属している組織のいずれかです。
+- モデルの名前を選択します。これはリポジトリの名前にもなります。
+- モデルが公開か非公開かを選択します。
+- モデルのライセンス使用方法を指定します。
+
+その後、**Files**タブをクリックし、**Add file**ボタンをクリックしてリポジトリに新しいファイルをアップロードします。次に、ファイルをドラッグアンドドロップしてアップロードし、コミットメッセージを追加します。
+
+
+
+## Add a model card
+
+ユーザーがモデルの機能、制限、潜在的な偏り、倫理的な考慮事項を理解できるようにするために、モデルリポジトリにモデルカードを追加してください。モデルカードは`README.md`ファイルで定義されます。モデルカードを追加する方法:
+
+* 手動で`README.md`ファイルを作成およびアップロードする。
+* モデルリポジトリ内の**Edit model card**ボタンをクリックする。
+
+モデルカードに含めるべき情報の例については、DistilBert [モデルカード](https://huggingface.co/distilbert/distilbert-base-uncased)をご覧ください。`README.md`ファイルで制御できる他のオプション、例えばモデルの炭素フットプリントやウィジェットの例などについての詳細は、[こちらのドキュメンテーション](https://huggingface.co/docs/hub/models-cards)を参照してください。
+
+
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_summary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..8f8b6af48cc17b05f80f06ca3b75991ad68a2d7c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/model_summary.md
@@ -0,0 +1,110 @@
+
+
+# The Transformer model family
+
+2017年に導入されて以来、[元のTransformer](https://arxiv.org/abs/1706.03762)モデルは、自然言語処理(NLP)のタスクを超える多くの新しいエキサイティングなモデルをインスパイアしました。[タンパク質の折りたたまれた構造を予測](https://huggingface.co/blog/deep-learning-with-proteins)するモデル、[チーターを走らせるためのトレーニング](https://huggingface.co/blog/train-decision-transformers)するモデル、そして[時系列予測](https://huggingface.co/blog/time-series-transformers)のためのモデルなどがあります。Transformerのさまざまなバリアントが利用可能ですが、大局を見落とすことがあります。これらのすべてのモデルに共通するのは、元のTransformerアーキテクチャに基づいていることです。一部のモデルはエンコーダまたはデコーダのみを使用し、他のモデルは両方を使用します。これは、Transformerファミリー内のモデルの高レベルの違いをカテゴライズし、調査するための有用な分類法を提供し、以前に出会ったことのないTransformerを理解するのに役立ちます。
+
+元のTransformerモデルに慣れていないか、リフレッシュが必要な場合は、Hugging Faceコースの[Transformerの動作原理](https://huggingface.co/course/chapter1/4?fw=pt)章をチェックしてください。
+
+
+ VIDEO
+
+
+## Computer vision
+
+
+
+### Convolutional network
+
+長い間、畳み込みネットワーク(CNN)はコンピュータビジョンのタスクにおいて支配的なパラダイムでしたが、[ビジョンTransformer](https://arxiv.org/abs/2010.11929)はそのスケーラビリティと効率性を示しました。それでも、一部のCNNの最高の特性、特に特定のタスクにとっては非常に強力な翻訳不変性など、一部のTransformerはアーキテクチャに畳み込みを組み込んでいます。[ConvNeXt](model_doc/convnext)は、畳み込みを現代化するためにTransformerから設計の選択肢を取り入れ、例えば、ConvNeXtは画像をパッチに分割するために重なり合わないスライディングウィンドウと、グローバル受容野を増加させるための大きなカーネルを使用します。ConvNeXtは、メモリ効率を向上させ、パフォーマンスを向上させるためにいくつかのレイヤーデザインの選択肢も提供し、Transformerと競合的になります!
+
+
+### Encoder[[cv-encoder]]
+
+[ビジョン トランスフォーマー(ViT)](model_doc/vit) は、畳み込みを使用しないコンピュータビジョンタスクの扉を開けました。ViT は標準のトランスフォーマーエンコーダーを使用しますが、画像を扱う方法が主要なブレークスルーでした。画像を固定サイズのパッチに分割し、それらをトークンのように使用して埋め込みを作成します。ViT は、当時のCNNと競争力のある結果を示すためにトランスフォーマーの効率的なアーキテクチャを活用しましたが、トレーニングに必要なリソースが少なくて済みました。ViT に続いて、セグメンテーションや検出などの密なビジョンタスクを処理できる他のビジョンモデルも登場しました。
+
+これらのモデルの1つが[Swin](model_doc/swin) トランスフォーマーです。Swin トランスフォーマーは、より小さなサイズのパッチから階層的な特徴マップ(CNNのようで ViT とは異なります)を構築し、深層のパッチと隣接するパッチとマージします。注意はローカルウィンドウ内でのみ計算され、ウィンドウは注意のレイヤー間でシフトされ、モデルがより良く学習するのをサポートする接続を作成します。Swin トランスフォーマーは階層的な特徴マップを生成できるため、セグメンテーションや検出などの密な予測タスクに適しています。[SegFormer](model_doc/segformer) も階層的な特徴マップを構築するためにトランスフォーマーエンコーダーを使用しますが、すべての特徴マップを組み合わせて予測するためにシンプルなマルチレイヤーパーセプトロン(MLP)デコーダーを追加します。
+
+BeIT および ViTMAE などの他のビジョンモデルは、BERTの事前トレーニング目標からインスピレーションを得ました。[BeIT](model_doc/beit) は *masked image modeling (MIM)* によって事前トレーニングされています。画像パッチはランダムにマスクされ、画像も視覚トークンにトークン化されます。BeIT はマスクされたパッチに対応する視覚トークンを予測するようにトレーニングされます。[ViTMAE](model_doc/vitmae) も似たような事前トレーニング目標を持っており、視覚トークンの代わりにピクセルを予測する必要があります。異例なのは画像パッチの75%がマスクされていることです!デコーダーはマスクされたトークンとエンコードされたパッチからピクセルを再構築します。事前トレーニングの後、デコーダーは捨てられ、エンコーダーはダウンストリームのタスクで使用できる状態です。
+
+### Decoder[[cv-decoder]]
+
+デコーダーのみのビジョンモデルは珍しいです。なぜなら、ほとんどのビジョンモデルは画像表現を学ぶためにエンコーダーを使用するからです。しかし、画像生成などのユースケースでは、デコーダーは自然な適応です。これは、GPT-2などのテキスト生成モデルから見てきたように、[ImageGPT](model_doc/imagegpt) でも同様のアーキテクチャを使用しますが、シーケンス内の次のトークンを予測する代わりに、画像内の次のピクセルを予測します。画像生成に加えて、ImageGPT は画像分類のためにもファインチューニングできます。
+
+### Encoder-decoder[[cv-encoder-decoder]]
+
+ビジョンモデルは一般的にエンコーダー(バックボーンとも呼ばれます)を使用して重要な画像特徴を抽出し、それをトランスフォーマーデコーダーに渡すために使用します。[DETR](model_doc/detr) は事前トレーニング済みのバックボーンを持っていますが、オブジェクト検出のために完全なトランスフォーマーエンコーダーデコーダーアーキテクチャも使用しています。エンコーダーは画像表現を学び、デコーダー内のオブジェクトクエリ(各オブジェクトクエリは画像内の領域またはオブジェクトに焦点を当てた学習された埋め込みです)と組み合わせます。DETR は各オブジェクトクエリに対する境界ボックスの座標とクラスラベルを予測します。
+
+## Natural lanaguage processing
+
+
+
+### Encoder[[nlp-encoder]]
+
+[BERT](model_doc/bert) はエンコーダー専用のTransformerで、入力の一部のトークンをランダムにマスクして他のトークンを見ないようにしています。これにより、トークンをマスクした文脈に基づいてマスクされたトークンを予測することが事前トレーニングの目標です。これにより、BERTは入力のより深いかつ豊かな表現を学習するのに左右の文脈を完全に活用できます。しかし、BERTの事前トレーニング戦略にはまだ改善の余地がありました。[RoBERTa](model_doc/roberta) は、トレーニングを長時間行い、より大きなバッチでトレーニングし、事前処理中に一度だけでなく各エポックでトークンをランダムにマスクし、次文予測の目標を削除する新しい事前トレーニングレシピを導入することでこれを改善しました。
+
+性能を向上させる主要な戦略はモデルのサイズを増やすことですが、大規模なモデルのトレーニングは計算コストがかかります。計算コストを削減する方法の1つは、[DistilBERT](model_doc/distilbert) のような小さなモデルを使用することです。DistilBERTは[知識蒸留](https://arxiv.org/abs/1503.02531) - 圧縮技術 - を使用して、BERTのほぼすべての言語理解機能を保持しながら、より小さなバージョンを作成します。
+
+しかし、ほとんどのTransformerモデルは引き続きより多くのパラメータに焦点を当て、トレーニング効率を向上させる新しいモデルが登場しています。[ALBERT](model_doc/albert) は、2つの方法でパラメータの数を減らすことによってメモリ消費量を削減します。大きな語彙埋め込みを2つの小さな行列に分割し、レイヤーがパラメータを共有できるようにします。[DeBERTa](model_doc/deberta) は、単語とその位置を2つのベクトルで別々にエンコードする解かれた注意機構を追加しました。注意はこれらの別々のベクトルから計算されます。単語と位置の埋め込みが含まれる単一のベクトルではなく、[Longformer](model_doc/longformer) は、特に長いシーケンス長のドキュメントを処理するために注意をより効率的にすることに焦点を当てました。固定されたウィンドウサイズの周りの各トークンから計算されるローカルウィンドウ付き注意(特定のタスクトークン(分類のための `[CLS]` など)のみのためのグローバルな注意を含む)の組み合わせを使用して、完全な注意行列ではなく疎な注意行列を作成します。
+
+
+### Decoder[[nlp-decoder]]
+
+[GPT-2](model_doc/gpt2)は、シーケンス内の次の単語を予測するデコーダー専用のTransformerです。モデルは先を見ることができないようにトークンを右にマスクし、"のぞき見"を防ぎます。大量のテキストを事前トレーニングしたことにより、GPT-2はテキスト生成が非常に得意で、テキストが正確であることがあるにしても、時折正確ではないことがあります。しかし、GPT-2にはBERTの事前トレーニングからの双方向コンテキストが不足しており、特定のタスクには適していませんでした。[XLNET](model_doc/xlnet)は、双方向に学習できる順列言語モデリング目標(PLM)を使用することで、BERTとGPT-2の事前トレーニング目標のベストを組み合わせています。
+
+GPT-2の後、言語モデルはさらに大きく成長し、今では*大規模言語モデル(LLM)*として知られています。大規模なデータセットで事前トレーニングされれば、LLMはほぼゼロショット学習を示すことがあります。[GPT-J](model_doc/gptj)は、6Bのパラメータを持つLLMで、400Bのトークンでトレーニングされています。GPT-Jには[OPT](model_doc/opt)が続き、そのうち最大のモデルは175Bで、180Bのトークンでトレーニングされています。同じ時期に[BLOOM](model_doc/bloom)がリリースされ、このファミリーの最大のモデルは176Bのパラメータを持ち、46の言語と13のプログラミング言語で366Bのトークンでトレーニングされています。
+
+### Encoder-decoder[[nlp-encoder-decoder]]
+
+[BART](model_doc/bart)は、元のTransformerアーキテクチャを保持していますが、事前トレーニング目標を*テキスト補完*の破損に変更しています。一部のテキストスパンは単一の`mask`トークンで置換されます。デコーダーは破損していないトークンを予測し(未来のトークンはマスクされます)、エンコーダーの隠れた状態を使用して予測を補助します。[Pegasus](model_doc/pegasus)はBARTに似ていますが、Pegasusはテキストスパンの代わりに文全体をマスクします。マスクされた言語モデリングに加えて、Pegasusはギャップ文生成(GSG)によって事前トレーニングされています。GSGの目標は、文書に重要な文をマスクし、それらを`mask`トークンで置換することです。デコーダーは残りの文から出力を生成しなければなりません。[T5](model_doc/t5)は、すべてのNLPタスクを特定のプレフィックスを使用してテキスト対テキストの問題に変換するよりユニークなモデルです。たとえば、プレフィックス`Summarize:`は要約タスクを示します。T5は教師ありトレーニング(GLUEとSuperGLUE)と自己教師ありトレーニング(トークンの15%をランダムにサンプルしドロップアウト)によって事前トレーニングされています。
+
+
+## Audio
+
+
+
+### Encoder[[audio-encoder]]
+
+[Wav2Vec2](model_doc/wav2vec2) は、生のオーディオ波形から直接音声表現を学習するためのTransformerエンコーダーを使用します。これは、対照的なタスクで事前学習され、一連の偽の表現から真の音声表現を特定します。 [HuBERT](model_doc/hubert) はWav2Vec2に似ていますが、異なるトレーニングプロセスを持っています。ターゲットラベルは、類似したオーディオセグメントがクラスタに割り当てられ、これが隠れユニットになるクラスタリングステップによって作成されます。隠れユニットは埋め込みにマップされ、予測を行います。
+
+### Encoder-decoder[[audio-encoder-decoder]]
+
+[Speech2Text](model_doc/speech_to_text) は、自動音声認識(ASR)および音声翻訳のために設計された音声モデルです。このモデルは、オーディオ波形から抽出されたログメルフィルターバンクフィーチャーを受け入れ、事前トレーニングされた自己回帰的にトランスクリプトまたは翻訳を生成します。 [Whisper](model_doc/whisper) もASRモデルですが、他の多くの音声モデルとは異なり、✨ ラベル付き ✨ オーディオトランスクリプションデータを大量に事前に学習して、ゼロショットパフォーマンスを実現します。データセットの大部分には非英語の言語も含まれており、Whisperは低リソース言語にも使用できます。構造的には、WhisperはSpeech2Textに似ています。オーディオ信号はエンコーダーによってエンコードされたログメルスペクトログラムに変換されます。デコーダーはエンコーダーの隠れ状態と前のトークンからトランスクリプトを自己回帰的に生成します。
+
+## Multimodal
+
+
+
+### Encoder[[mm-encoder]]
+
+[VisualBERT](model_doc/visual_bert) は、BERTの後にリリースされたビジョン言語タスク向けのマルチモーダルモデルです。これはBERTと事前トレーニングされた物体検出システムを組み合わせ、画像特徴をビジュアル埋め込みに抽出し、テキスト埋め込みと一緒にBERTに渡します。VisualBERTは非マスクテキストを基にしたマスクテキストを予測し、テキストが画像と整合しているかどうかも予測する必要があります。ViTがリリースされた際、[ViLT](model_doc/vilt) は画像埋め込みを取得するためにこの方法を採用しました。画像埋め込みはテキスト埋め込みと共に共同で処理されます。それから、ViLTは画像テキストマッチング、マスク言語モデリング、および全単語マスキングによる事前トレーニングが行われます。
+
+[CLIP](model_doc/clip) は異なるアプローチを取り、(`画像`、`テキスト`) のペア予測を行います。画像エンコーダー(ViT)とテキストエンコーダー(Transformer)は、(`画像`、`テキスト`) ペアデータセット上で共同トレーニングされ、(`画像`、`テキスト`) ペアの画像とテキストの埋め込みの類似性を最大化します。事前トレーニング後、CLIPを使用して画像からテキストを予測したり、その逆を行うことができます。[OWL-ViT](model_doc/owlvit) は、ゼロショット物体検出のバックボーンとしてCLIPを使用しています。事前トレーニング後、物体検出ヘッドが追加され、(`クラス`、`バウンディングボックス`) ペアに対するセット予測が行われます。
+
+### Encoder-decoder[[mm-encoder-decoder]]
+
+光学文字認識(OCR)は、通常、画像を理解しテキストを生成するために複数のコンポーネントが関与するテキスト認識タスクです。 [TrOCR](model_doc/trocr) は、エンドツーエンドのTransformerを使用してこのプロセスを簡略化します。エンコーダーは画像を固定サイズのパッチとして処理するためのViTスタイルのモデルであり、デコーダーはエンコーダーの隠れ状態を受け入れ、テキストを自己回帰的に生成します。[Donut](model_doc/donut) はOCRベースのアプローチに依存しないより一般的なビジュアルドキュメント理解モデルで、エンコーダーとしてSwin Transformer、デコーダーとして多言語BARTを使用します。 Donutは画像とテキストの注釈に基づいて次の単語を予測することにより、テキストを読むために事前トレーニングされます。デコーダーはプロンプトを与えられたトークンシーケンスを生成します。プロンプトは各ダウンストリームタスクごとに特別なトークンを使用して表現されます。例えば、ドキュメントの解析には`解析`トークンがあり、エンコーダーの隠れ状態と組み合わされてドキュメントを構造化された出力フォーマット(JSON)に解析します。
+
+## Reinforcement learning
+
+
+
+### Decoder[[rl-decoder]]
+
+意思決定と軌跡トランスフォーマーは、状態、アクション、報酬をシーケンスモデリングの問題として捉えます。 [Decision Transformer](model_doc/decision_transformer) は、リターン・トゥ・ゴー、過去の状態、およびアクションに基づいて将来の希望リターンにつながるアクションの系列を生成します。最後の *K* タイムステップでは、3つのモダリティそれぞれがトークン埋め込みに変換され、将来のアクショントークンを予測するためにGPTのようなモデルによって処理されます。[Trajectory Transformer](model_doc/trajectory_transformer) も状態、アクション、報酬をトークン化し、GPTアーキテクチャで処理します。報酬調整に焦点を当てたDecision Transformerとは異なり、Trajectory Transformerはビームサーチを使用して将来のアクションを生成します。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/multilingual.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/multilingual.md
new file mode 100644
index 0000000000000000000000000000000000000000..39524195f88810e018e29398ad78f65f518522f2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/multilingual.md
@@ -0,0 +1,178 @@
+
+
+# 推論のための多言語モデル
+
+[[open-in-colab]]
+
+🤗 Transformers にはいくつかの多言語モデルがあり、それらの推論の使用方法は単一言語モデルとは異なります。ただし、多言語モデルの使用方法がすべて異なるわけではありません。 [google-bert/bert-base-multilingual-uncased](https://huggingface.co/google-bert/bert-base-multilingual-uncased) などの一部のモデルは、単一言語モデルと同様に使用できます。 このガイドでは、推論のために使用方法が異なる多言語モデルをどのように使うかを示します。
+
+## XLM
+
+XLM には10の異なるチェックポイントがあり、そのうちの1つだけが単一言語です。 残りの9つのモデルチェックポイントは、言語埋め込みを使用するチェックポイントと使用しないチェックポイントの2つのカテゴリに分けることができます。
+
+### 言語の埋め込みがある XLM
+
+次の XLM モデルは、言語の埋め込みを使用して、推論で使用される言語を指定します。
+
+- `FacebookAI/xlm-mlm-ende-1024` (マスク化された言語モデリング、英語-ドイツ語)
+- `FacebookAI/xlm-mlm-enfr-1024` (マスク化された言語モデリング、英語-フランス語)
+- `FacebookAI/xlm-mlm-enro-1024` (マスク化された言語モデリング、英語-ルーマニア語)
+- `FacebookAI/xlm-mlm-xnli15-1024` (マスク化された言語モデリング、XNLI 言語)
+- `FacebookAI/xlm-mlm-tlm-xnli15-1024` (マスク化された言語モデリング + 翻訳 + XNLI 言語)
+- `FacebookAI/xlm-clm-enfr-1024` (因果言語モデリング、英語-フランス語)
+- `FacebookAI/xlm-clm-ende-1024` (因果言語モデリング、英語-ドイツ語)
+
+言語の埋め込みは、モデルに渡される `input_ids` と同じ形状のテンソルとして表されます。 これらのテンソルの値は、使用される言語に依存し、トークナイザーの `lang2id` および `id2lang` 属性によって識別されます。
+
+この例では、`FacebookAI/xlm-clm-enfr-1024` チェックポイントをロードします (因果言語モデリング、英語-フランス語)。
+
+```py
+>>> import torch
+>>> from transformers import XLMTokenizer, XLMWithLMHeadModel
+
+>>> tokenizer = XLMTokenizer.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+>>> model = XLMWithLMHeadModel.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+```
+
+トークナイザーの `lang2id` 属性は、このモデルの言語とその ID を表示します。
+
+```py
+>>> print(tokenizer.lang2id)
+{'en': 0, 'fr': 1}
+```
+
+次に、入力例を作成します。
+
+```py
+>>> input_ids = torch.tensor([tokenizer.encode("Wikipedia was used to")]) # batch size of 1
+```
+
+言語 ID を `en` に設定し、それを使用して言語の埋め込みを定義します。 言語の埋め込みは、英語の言語 ID であるため、`0` で埋められたテンソルです。 このテンソルは `input_ids` と同じサイズにする必要があります。
+
+```py
+>>> language_id = tokenizer.lang2id["en"] # 0
+>>> langs = torch.tensor([language_id] * input_ids.shape[1]) # torch.tensor([0, 0, 0, ..., 0])
+
+>>> # We reshape it to be of size (batch_size, sequence_length)
+>>> langs = langs.view(1, -1) # is now of shape [1, sequence_length] (we have a batch size of 1)
+```
+
+これで、`input_ids` と言語の埋め込みをモデルに渡すことができます。
+
+```py
+>>> outputs = model(input_ids, langs=langs)
+```
+
+[run_generation.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-generation/run_generation.py) スクリプトは、`xlm-clm` チェックポイントを使用して、言語が埋め込まれたテキストを生成できます。
+
+### 言語の埋め込みがないXLM
+
+次の XLM モデルは、推論中に言語の埋め込みを必要としません。
+
+- `FacebookAI/xlm-mlm-17-1280` (マスク化された言語モデリング、17の言語)
+- `FacebookAI/xlm-mlm-100-1280` (マスク化された言語モデリング、100の言語)
+
+これらのモデルは、以前の XLM チェックポイントとは異なり、一般的な文の表現に使用されます。
+
+## BERT
+
+以下の BERT モデルは、多言語タスクに使用できます。
+
+- `google-bert/bert-base-multilingual-uncased` (マスク化された言語モデリング + 次の文の予測、102の言語)
+- `google-bert/bert-base-multilingual-cased` (マスク化された言語モデリング + 次の文の予測、104の言語)
+
+これらのモデルは、推論中に言語の埋め込みを必要としません。 文脈から言語を識別し、それに応じて推測する必要があります。
+
+## XLM-RoBERTa
+
+次の XLM-RoBERTa モデルは、多言語タスクに使用できます。
+
+- `FacebookAI/xlm-roberta-base` (マスク化された言語モデリング、100の言語)
+- `FacebookAI/xlm-roberta-large` (マスク化された言語モデリング、100の言語)
+
+XLM-RoBERTa は、100の言語で新しく作成およびクリーニングされた2.5 TB の CommonCrawl データでトレーニングされました。 これは、分類、シーケンスのラベル付け、質問応答などのダウンストリームタスクで、mBERT や XLM などの以前にリリースされた多言語モデルを大幅に改善します。
+
+## M2M100
+
+次の M2M100 モデルは、多言語翻訳に使用できます。
+
+- `facebook/m2m100_418M` (翻訳)
+- `facebook/m2m100_1.2B` (翻訳)
+
+この例では、`facebook/m2m100_418M` チェックポイントをロードして、中国語から英語に翻訳します。 トークナイザーでソース言語を設定できます。
+
+```py
+>>> from transformers import M2M100ForConditionalGeneration, M2M100Tokenizer
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> chinese_text = "不要插手巫師的事務, 因為他們是微妙的, 很快就會發怒."
+
+>>> tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M", src_lang="zh")
+>>> model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M")
+```
+
+テキストをトークン化します。
+
+```py
+>>> encoded_zh = tokenizer(chinese_text, return_tensors="pt")
+```
+
+M2M100 は、最初に生成されたトークンとしてターゲット言語 ID を強制的にターゲット言語に翻訳します。 英語に翻訳するには、`generate` メソッドで `forced_bos_token_id` を `en` に設定します。
+
+```py
+>>> generated_tokens = model.generate(**encoded_zh, forced_bos_token_id=tokenizer.get_lang_id("en"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+'Do not interfere with the matters of the witches, because they are delicate and will soon be angry.'
+```
+
+## MBart
+
+多言語翻訳には、次の MBart モデルを使用できます。
+
+- `facebook/mbart-large-50-one-to-many-mmt` (One-to-many multilingual machine translation, 50 languages)
+- `facebook/mbart-large-50-many-to-many-mmt` (Many-to-many multilingual machine translation, 50 languages)
+- `facebook/mbart-large-50-many-to-one-mmt` (Many-to-one multilingual machine translation, 50 languages)
+- `facebook/mbart-large-50` (Multilingual translation, 50 languages)
+- `facebook/mbart-large-cc25`
+
+この例では、`facebook/mbart-large-50-many-to-many-mmt` チェックポイントをロードして、フィンランド語を英語に翻訳します。トークナイザーでソース言語を設定できます。
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> fi_text = "Älä sekaannu velhojen asioihin, sillä ne ovat hienovaraisia ja nopeasti vihaisia."
+
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/mbart-large-50-many-to-many-mmt", src_lang="fi_FI")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
+```
+
+テキストをトークン化します。
+
+```py
+>>> encoded_en = tokenizer(en_text, return_tensors="pt")
+```
+
+MBart は、最初に生成されたトークンとしてターゲット言語 ID を強制的にターゲット言語に翻訳します。 英語に翻訳するには、`generate` メソッドで `forced_bos_token_id` を `en` に設定します。
+
+```py
+>>> generated_tokens = model.generate(**encoded_en, forced_bos_token_id=tokenizer.lang_code_to_id("en_XX"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+"Don't interfere with the wizard's affairs, because they are subtle, will soon get angry."
+```
+
+`facebook/mbart-large-50-many-to-one-mmt` チェックポイントを使用している場合、最初に生成されたトークンとしてターゲット言語 ID を強制する必要はありません。それ以外の場合、使用方法は同じです。
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/pad_truncation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/pad_truncation.md
new file mode 100644
index 0000000000000000000000000000000000000000..4da23fd82e0f49d3cba205d49bbbc76d8ea28e32
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/pad_truncation.md
@@ -0,0 +1,63 @@
+
+
+# Padding and truncation
+
+バッチ入力はしばしば異なる長さであり、固定サイズのテンソルに変換できないため、変動する長さのバッチから長方形のテンソルを作成するための戦略として、パディングと切り詰めがあります。パディングは、短いシーケンスがバッチ内の最長シーケンスまたはモデルが受け入れる最大長と同じ長さになるように、特別な**パディングトークン**を追加します。切り詰めは、長いシーケンスを切り詰めることで逆方向に機能します。
+
+ほとんどの場合、バッチを最長シーケンスの長さにパディングし、モデルが受け入れる最大長に切り詰めることで、うまく動作します。ただし、APIはそれ以上の戦略もサポートしています。必要な3つの引数は次のとおりです:`padding`、`truncation`、および `max_length`。
+
+`padding`引数はパディングを制御します。ブール値または文字列であることができます:
+
+ - `True`または`'longest'`:バッチ内の最長シーケンスにパディングを追加します(シーケンスが1つしか提供されない場合、パディングは適用されません)。
+ - `max_length'`:`max_length`引数で指定された長さまでパディングを追加します。または`max_length`が提供されていない場合はモデルが受け入れる最大長(`max_length=None`)。シーケンスが1つしか提供されている場合でも、パディングは適用されます。
+ - `False`または`'do_not_pad'`:パディングは適用されません。これがデフォルトの動作です。
+
+`truncation`引数は切り詰めを制御します。ブール値または文字列であることができます:
+
+ - `True`または`'longest_first'`:最大長を`max_length`引数で指定するか、モデルが受け入れる最大長(`max_length=None`)まで切り詰めます。これはトークンごとに切り詰め、適切な長さに達するまでペア内の最長シーケンスからトークンを削除します。
+ - `'only_second'`:最大長を`max_length`引数で指定するか、モデルが受け入れる最大長(`max_length=None`)まで切り詰めます。これはペアの2番目の文だけを切り詰めます(シーケンスのペアまたはシーケンスのバッチのペアが提供された場合)。
+ - `'only_first'`:最大長を`max_length`引数で指定するか、モデルが受け入れる最大長(`max_length=None`)まで切り詰めます。これはペアの最初の文だけを切り詰めます(シーケンスのペアまたはシーケンスのバッチのペアが提供された場合)。
+ - `False`または`'do_not_truncate'`:切り詰めは適用されません。これがデフォルトの動作です。
+
+`max_length`引数はパディングと切り詰めの長さを制御します。整数または`None`であり、この場合、モデルが受け入れる最大入力長にデフォルトで設定されます。モデルに特定の最大入力長がない場合、`max_length`への切り詰めまたはパディングは無効になります。
+
+以下の表は、パディングと切り詰めを設定する推奨方法を要約しています。以下の例のいずれかで入力シーケンスのペアを使用する場合、`truncation=True`を`['only_first', 'only_second', 'longest_first']`で選択した`STRATEGY`に置き換えることができます。つまり、`truncation='only_second'`または`truncation='longest_first'`を使用して、ペア内の両方のシーケンスを前述のように切り詰める方法を制御できます。
+
+
+
+| Truncation | Padding | Instruction |
+|--------------------------------------|-----------------------------------|---------------------------------------------------------------------------------------------|
+| no truncation | no padding | `tokenizer(batch_sentences)` |
+| | padding to max sequence in batch | `tokenizer(batch_sentences, padding=True)` or |
+| | | `tokenizer(batch_sentences, padding='longest')` |
+| | padding to max model input length | `tokenizer(batch_sentences, padding='max_length')` |
+| | padding to specific length | `tokenizer(batch_sentences, padding='max_length', max_length=42)` |
+| | padding to a multiple of a value | `tokenizer(batch_sentences, padding=True, pad_to_multiple_of=8)` |
+| truncation to max model input length | no padding | `tokenizer(batch_sentences, truncation=True)` or |
+| | | `tokenizer(batch_sentences, truncation=STRATEGY)` |
+| | padding to max sequence in batch | `tokenizer(batch_sentences, padding=True, truncation=True)` or |
+| | | `tokenizer(batch_sentences, padding=True, truncation=STRATEGY)` |
+| | padding to max model input length | `tokenizer(batch_sentences, padding='max_length', truncation=True)` or |
+| | | `tokenizer(batch_sentences, padding='max_length', truncation=STRATEGY)` |
+| | padding to specific length | Not possible |
+| truncation to specific length | no padding | `tokenizer(batch_sentences, truncation=True, max_length=42)` or |
+| | | `tokenizer(batch_sentences, truncation=STRATEGY, max_length=42)` |
+| | padding to max sequence in batch | `tokenizer(batch_sentences, padding=True, truncation=True, max_length=42)` or |
+| | | `tokenizer(batch_sentences, padding=True, truncation=STRATEGY, max_length=42)` |
+| | padding to max model input length | Not possible |
+| | padding to specific length | `tokenizer(batch_sentences, padding='max_length', truncation=True, max_length=42)` or |
+| | | `tokenizer(batch_sentences, padding='max_length', truncation=STRATEGY, max_length=42)` |
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/peft.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/peft.md
new file mode 100644
index 0000000000000000000000000000000000000000..c3d195adbd97d777021911cdd382fff98f7fa00a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/peft.md
@@ -0,0 +1,214 @@
+
+
+
+# Load adapters with 🤗 PEFT
+
+[[open-in-colab]]
+
+[Parameter-Efficient Fine Tuning (PEFT)](https://huggingface.co/blog/peft) メソッドは、事前学習済みモデルのパラメータをファインチューニング中に凍結し、その上にわずかな訓練可能なパラメータ(アダプター)を追加するアプローチです。アダプターは、タスク固有の情報を学習するために訓練されます。このアプローチは、メモリ使用量が少なく、完全にファインチューニングされたモデルと比較して計算リソースを低く抑えつつ、同等の結果を生成することが示されています。
+
+PEFTで訓練されたアダプターは通常、完全なモデルのサイズよりも1桁小さく、共有、保存、読み込むのが便利です。
+
+
+
+
Hubに格納されているOPTForCausalLMモデルのアダプター重みは、モデルの全体サイズの約6MBで、モデル重みの全サイズは約700MBです。
+
+
+PEFTアダプターを`AutoModelFor`クラスまたは基本モデルクラス(`OPTForCausalLM`または`LlamaForCausalLM`など)で読み込むことができます。
+
+
+
+また、`load_adapter`メソッドを呼び出すことで、PEFTアダプターを読み込むこともできます:
+
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "facebook/opt-350m"
+peft_model_id = "ybelkada/opt-350m-lora"
+
+model = AutoModelForCausalLM.from_pretrained(model_id)
+model.load_adapter(peft_model_id)
+```
+
+## Load in 8bit or 4bit
+
+
+`bitsandbytes` 統合は、8ビットおよび4ビットの精度データ型をサポートしており、大規模なモデルを読み込む際にメモリを節約するのに役立ちます(詳細については `bitsandbytes` 統合の[ガイド](./quantization#bitsandbytes-integration)を参照してください)。[`~PreTrainedModel.from_pretrained`] に `load_in_8bit` または `load_in_4bit` パラメータを追加し、`device_map="auto"` を設定してモデルを効果的にハードウェアに分散配置できます:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+peft_model_id = "ybelkada/opt-350m-lora"
+model = AutoModelForCausalLM.from_pretrained(peft_model_id, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+
+## Add a new adapter
+
+既存のアダプターを持つモデルに新しいアダプターを追加するために [`~peft.PeftModel.add_adapter`] を使用できます。ただし、新しいアダプターは現在のアダプターと同じタイプである限り、これを行うことができます。たとえば、モデルに既存の LoRA アダプターがアタッチされている場合:
+
+
+```py
+from transformers import AutoModelForCausalLM, OPTForCausalLM, AutoTokenizer
+from peft import PeftConfig
+
+model_id = "facebook/opt-350m"
+model = AutoModelForCausalLM.from_pretrained(model_id)
+
+lora_config = LoraConfig(
+ target_modules=["q_proj", "k_proj"],
+ init_lora_weights=False
+)
+
+model.add_adapter(lora_config, adapter_name="adapter_1")
+```
+
+新しいアダプタを追加するには:
+
+
+```py
+# attach new adapter with same config
+model.add_adapter(lora_config, adapter_name="adapter_2")
+```
+
+[`~peft.PeftModel.set_adapter`] を使用して、どのアダプターを使用するかを設定できます:
+
+
+```py
+# use adapter_1
+model.set_adapter("adapter_1")
+output = model.generate(**inputs)
+print(tokenizer.decode(output_disabled[0], skip_special_tokens=True))
+
+# use adapter_2
+model.set_adapter("adapter_2")
+output_enabled = model.generate(**inputs)
+print(tokenizer.decode(output_enabled[0], skip_special_tokens=True))
+```
+
+## Enable and disable adapters
+
+モデルにアダプターを追加したら、アダプターモジュールを有効または無効にすることができます。アダプターモジュールを有効にするには、次の手順を実行します:
+
+```py
+from transformers import AutoModelForCausalLM, OPTForCausalLM, AutoTokenizer
+from peft import PeftConfig
+
+model_id = "facebook/opt-350m"
+adapter_model_id = "ybelkada/opt-350m-lora"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+text = "Hello"
+inputs = tokenizer(text, return_tensors="pt")
+
+model = AutoModelForCausalLM.from_pretrained(model_id)
+peft_config = PeftConfig.from_pretrained(adapter_model_id)
+
+# to initiate with random weights
+peft_config.init_lora_weights = False
+
+model.add_adapter(peft_config)
+model.enable_adapters()
+output = model.generate(**inputs)
+```
+
+アダプターモジュールを無効にするには:
+
+```py
+model.disable_adapters()
+output = model.generate(**inputs)
+```
+
+## Train a PEFT adapter
+
+PEFTアダプターは[`Trainer`]クラスでサポートされており、特定のユースケースに対してアダプターをトレーニングすることができます。数行のコードを追加するだけで済みます。たとえば、LoRAアダプターをトレーニングする場合:
+
+
+
+[`Trainer`]を使用したモデルの微調整に慣れていない場合は、[事前トレーニング済みモデルの微調整](training)チュートリアルをご覧ください。
+
+
+
+1. タスクタイプとハイパーパラメータに対するアダプターの構成を定義します(ハイパーパラメータの詳細については[`~peft.LoraConfig`]を参照してください)。
+
+
+```py
+from peft import LoraConfig
+
+peft_config = LoraConfig(
+ lora_alpha=16,
+ lora_dropout=0.1,
+ r=64,
+ bias="none",
+ task_type="CAUSAL_LM",
+)
+```
+
+2. モデルにアダプターを追加する。
+
+
+```py
+model.add_adapter(peft_config)
+```
+
+3. これで、モデルを [`Trainer`] に渡すことができます!
+
+```py
+trainer = Trainer(model=model, ...)
+trainer.train()
+```
+
+保存するトレーニング済みアダプタとそれを読み込むための手順:
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_hardware.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_hardware.md
new file mode 100644
index 0000000000000000000000000000000000000000..0d104ed3ddb0b366cd979b66d0f507c9a54e43af
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_hardware.md
@@ -0,0 +1,160 @@
+
+
+# Custom hardware for training
+
+モデルのトレーニングおよび推論に使用するハードウェアは、パフォーマンスに大きな影響を与えることがあります。GPUについて詳しく知りたい場合は、Tim Dettmerの優れた[ブログ記事](https://timdettmers.com/2020/09/07/which-gpu-for-deep-learning/)をチェックしてみてください。
+
+GPUセットアップの実用的なアドバイスをいくつか見てみましょう。
+
+## GPU
+より大きなモデルをトレーニングする場合、基本的には以下の3つのオプションがあります:
+
+- より大きなGPU
+- より多くのGPU
+- より多くのCPUおよびNVMe([DeepSpeed-Infinity](main_classes/deepspeed#nvme-support)によるオフロード)
+
+まず、単一のGPUを使用する場合から始めましょう。
+
+### Power and Cooling
+
+高価なハイエンドGPUを購入した場合、正しい電力供給と十分な冷却を提供することが重要です。
+
+**電力**:
+
+一部の高級コンシューマGPUカードには、2つまたは3つのPCI-E 8ピン電源ソケットがあります。カードにあるソケットの数だけ、独立した12V PCI-E 8ピンケーブルが接続されていることを確認してください。同じケーブルの一端にある2つの分岐(またはピッグテールケーブルとしても知られています)を使用しないでください。つまり、GPUに2つのソケットがある場合、PSUからカードに向けて2つのPCI-E 8ピンケーブルを使用し、1つのケーブルの端に2つのPCI-E 8ピンコネクタがあるものは使用しないでください!そうしないと、カードからのパフォーマンスを十分に引き出すことができません。
+
+各PCI-E 8ピン電源ケーブルは、PSU側の12Vレールに接続する必要があり、最大で150Wの電力を供給できます。
+
+一部のカードはPCI-E 12ピンコネクタを使用することがあり、これらは最大で500-600Wの電力を供給できます。
+
+低価格帯のカードは6ピンコネクタを使用することがあり、最大で75Wの電力を供給します。
+
+さらに、カードが必要とする安定した電圧を提供する高品質な電源ユニット(PSU)を使用する必要があります。
+
+もちろん、PSUにはカードを駆動するために十分な未使用の電力が必要です。
+
+**冷却**:
+
+GPUが過熱すると、スロットリングが開始され、フルパフォーマンスを提供しなくなり、過熱しすぎるとシャットダウンすることさえあります。
+
+GPUが重要な負荷の下でどのような温度を目指すべきかを正確に示すことは難しいですが、おそらく+80℃未満であれば良いでしょうが、それより低い方が良いです - おそらく70-75℃が優れた範囲でしょう。スロットリングの開始温度はおそらく84-90℃のあたりからでしょう。スロットリングによるパフォーマンスの低下以外にも、長時間にわたる非常に高い温度はGPUの寿命を短縮する可能性があります。
+
+次に、複数のGPUを持つ際に最も重要な側面の一つである接続について詳しく見てみましょう。
+
+### Multi-GPU Connectivity
+
+複数のGPUを使用する場合、カードの相互接続方法はトータルのトレーニング時間に大きな影響を与える可能性があります。GPUが同じ物理ノードにある場合、次のように実行できます:
+
+
+```bash
+nvidia-smi topo -m
+```
+
+もちろん、GPUがどのように相互接続されているかについて説明します。デュアルGPUを搭載し、NVLinkで接続されているマシンでは、おそらく以下のような情報が表示されるでしょう:
+
+```
+ GPU0 GPU1 CPU Affinity NUMA Affinity
+GPU0 X NV2 0-23 N/A
+GPU1 NV2 X 0-23 N/A
+```
+
+別のNVLinkなしのマシンでは、以下のような状況が発生するかもしれません:
+
+```
+ GPU0 GPU1 CPU Affinity NUMA Affinity
+GPU0 X PHB 0-11 N/A
+GPU1 PHB X 0-11 N/A
+```
+
+こちらが伝説です:
+
+```
+ X = Self
+ SYS = Connection traversing PCIe as well as the SMP interconnect between NUMA nodes (e.g., QPI/UPI)
+ NODE = Connection traversing PCIe as well as the interconnect between PCIe Host Bridges within a NUMA node
+ PHB = Connection traversing PCIe as well as a PCIe Host Bridge (typically the CPU)
+ PXB = Connection traversing multiple PCIe bridges (without traversing the PCIe Host Bridge)
+ PIX = Connection traversing at most a single PCIe bridge
+ NV# = Connection traversing a bonded set of # NVLinks
+```
+
+最初のレポートである `NV2` では、GPUは2つのNVLinkで接続されており、2番目のレポートである `PHB` では、典型的な消費者向けのPCIe+Bridgeセットアップが行われています。
+
+あなたのセットアップでどの種類の接続性があるかを確認してください。これらの接続方法のいくつかはカード間の通信を速くすることができます(例:NVLink)、他のものは遅くすることができます(例:PHB)。
+
+使用されるスケーラビリティソリューションの種類に応じて、接続速度は大きな影響を与えることも、小さな影響を与えることもあります。GPUがあまり頻繁に同期する必要がない場合、DDPのように、遅い接続の影響はそれほど重要ではありません。しかし、GPUが頻繁にメッセージを送信する必要がある場合、ZeRO-DPのように、高速の接続がより高速なトレーニングを実現するために非常に重要になります。
+
+#### NVlink
+
+[NVLink](https://en.wikipedia.org/wiki/NVLink) は、Nvidiaによって開発された有線のシリアルマルチレーンの近距離通信リンクです。
+
+各新世代では、より高速な帯域幅が提供されます。たとえば、[Nvidia Ampere GA102 GPU Architecture](https://www.nvidia.com/content/dam/en-zz/Solutions/geforce/ampere/pdf/NVIDIA-ampere-GA102-GPU-Architecture-Whitepaper-V1.pdf) からの引用です。
+
+> Third-Generation NVLink®
+> GA102 GPUs utilize NVIDIA’s third-generation NVLink interface, which includes four x4 links,
+> with each link providing 14.0625 GB/sec bandwidth in each direction between two GPUs. Four
+> links provide 56.25 GB/sec bandwidth in each direction, and 112.5 GB/sec total bandwidth
+> between two GPUs. Two RTX 3090 GPUs can be connected together for SLI using NVLink.
+> (Note that 3-Way and 4-Way SLI configurations are not supported.)
+
+したがって、`nvidia-smi topo -m` の出力の `NVX` レポートで取得する `X` が高いほど良いです。世代はあなたのGPUアーキテクチャに依存します。
+
+小さなサンプルのwikitextを使用したgpt2言語モデルのトレーニングの実行を比較しましょう。
+
+結果は次のとおりです:
+
+(ここに結果を挿入)
+
+上記のテキストの日本語訳を提供しました。Markdownコードとしてフォーマットしました。どんな他の質問があれば、お気軽にお知らせください!
+
+| NVlink | Time |
+| ----- | ---: |
+| Y | 101s |
+| N | 131s |
+
+
+NVLinkを使用すると、トレーニングが約23%速く完了することがわかります。2番目のベンチマークでは、`NCCL_P2P_DISABLE=1`を使用して、GPUがNVLinkを使用しないように指示しています。
+
+以下は、完全なベンチマークコードと出力です:
+
+
+```bash
+# DDP w/ NVLink
+
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 torchrun \
+--nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py --model_name_or_path openai-community/gpt2 \
+--dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 --do_train \
+--output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 101.9003, 'train_samples_per_second': 1.963, 'epoch': 0.69}
+
+# DDP w/o NVLink
+
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 NCCL_P2P_DISABLE=1 torchrun \
+--nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py --model_name_or_path openai-community/gpt2 \
+--dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 --do_train
+--output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 131.4367, 'train_samples_per_second': 1.522, 'epoch': 0.69}
+```
+
+Hardware: 2x TITAN RTX 24GB each + NVlink with 2 NVLinks (`NV2` in `nvidia-smi topo -m`)
+Software: `pytorch-1.8-to-be` + `cuda-11.0` / `transformers==4.3.0.dev0`
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_infer_cpu.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_infer_cpu.md
new file mode 100644
index 0000000000000000000000000000000000000000..d23ae65f309f41c044e5df8c93ba4945947d5a28
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_infer_cpu.md
@@ -0,0 +1,74 @@
+
+
+
+# Efficient Inference on CPU
+
+このガイドは、CPU上で大規模なモデルの効率的な推論に焦点を当てています。
+
+## `BetterTransformer` for faster inference
+
+最近、テキスト、画像、および音声モデルのCPU上での高速な推論のために`BetterTransformer`を統合しました。詳細については、この統合に関するドキュメンテーションを[こちら](https://huggingface.co/docs/optimum/bettertransformer/overview)で確認してください。
+
+## PyTorch JITモード(TorchScript)
+TorchScriptは、PyTorchコードからシリアライズ可能で最適化可能なモデルを作成する方法です。任意のTorchScriptプログラムは、Python依存性のないプロセスで保存およびロードできます。
+デフォルトのイーガーモードと比較して、PyTorchのjitモードは通常、オペレーターフュージョンなどの最適化手法によりモデル推論のパフォーマンスが向上します。
+
+TorchScriptの簡単な紹介については、[PyTorch TorchScriptチュートリアル](https://pytorch.org/tutorials/beginner/Intro_to_TorchScript_tutorial.html#tracing-modules)を参照してください。
+
+### JITモードでのIPEXグラフ最適化
+Intel® Extension for PyTorchは、Transformersシリーズモデルのjitモードにさらなる最適化を提供します。Intel® Extension for PyTorchをjitモードで使用することを強くお勧めします。Transformersモデルからよく使用されるオペレーターパターンのいくつかは、既にIntel® Extension for PyTorchでjitモードのフュージョンに対応しています。これらのフュージョンパターン(Multi-head-attentionフュージョン、Concat Linear、Linear+Add、Linear+Gelu、Add+LayerNormフュージョンなど)は有効でパフォーマンスが良いです。フュージョンの利点は、ユーザーに透過的に提供されます。分析によれば、最も人気のある質問応答、テキスト分類、トークン分類のNLPタスクの約70%が、これらのフュージョンパターンを使用してFloat32精度とBFloat16混合精度の両方でパフォーマンスの利点を得ることができます。
+
+[IPEXグラフ最適化の詳細情報](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/features/graph_optimization.html)を確認してください。
+
+#### IPEX installation:
+
+IPEXのリリースはPyTorchに従っています。[IPEXのインストール方法](https://intel.github.io/intel-extension-for-pytorch/)を確認してください。
+
+### Usage of JIT-mode
+Trainerで評価または予測のためにJITモードを有効にするには、ユーザーはTrainerコマンド引数に`jit_mode_eval`を追加する必要があります。
+
+
+
+PyTorch >= 1.14.0の場合、jitモードはjit.traceでdict入力がサポートされているため、予測と評価に任意のモデルに利益をもたらす可能性があります。
+
+PyTorch < 1.14.0の場合、jitモードはforwardパラメーターの順序がjit.traceのタプル入力の順序と一致するモデルに利益をもたらす可能性があります(質問応答モデルなど)。jit.traceがタプル入力の順序と一致しない場合、テキスト分類モデルなど、jit.traceは失敗し、これをフォールバックさせるために例外でキャッチしています。ログはユーザーに通知するために使用されます。
+
+
+
+[Transformers質問応答の使用例](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)を参考にしてください。
+
+- Inference using jit mode on CPU:
+python run_qa.py \
+--model_name_or_path csarron/bert-base-uncased-squad-v1 \
+--dataset_name squad \
+--do_eval \
+--max_seq_length 384 \
+--doc_stride 128 \
+--output_dir /tmp/ \
+--no_cuda \
+--jit_mode_eval
+
+- Inference with IPEX using jit mode on CPU:
+python run_qa.py \
+--model_name_or_path csarron/bert-base-uncased-squad-v1 \
+--dataset_name squad \
+--do_eval \
+--max_seq_length 384 \
+--doc_stride 128 \
+--output_dir /tmp/ \
+--no_cuda \
+--use_ipex \
+--jit_mode_eval
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_infer_gpu_many.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_infer_gpu_many.md
new file mode 100644
index 0000000000000000000000000000000000000000..18a19c849eb2c7536d13303d640d3f1c238c0757
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_infer_gpu_many.md
@@ -0,0 +1,127 @@
+
+
+# Efficient Inference on a Multiple GPUs
+
+この文書には、複数のGPUで効率的に推論を行う方法に関する情報が含まれています。
+
+
+注意: 複数のGPUセットアップは、[単一のGPUセクション](./perf_infer_gpu_one)で説明されているほとんどの戦略を使用できます。ただし、より良い使用法のために使用できる簡単なテクニックについても認識しておく必要があります。
+
+
+
+## Flash Attention 2
+
+Flash Attention 2の統合は、複数のGPUセットアップでも機能します。詳細については、[単一のGPUセクション](./perf_infer_gpu_one#Flash-Attention-2)の適切なセクションをご覧ください。
+
+## BetterTransformer
+
+[BetterTransformer](https://huggingface.co/docs/optimum/bettertransformer/overview)は、🤗 TransformersモデルをPyTorchネイティブの高速実行パスを使用するように変換し、その下でFlash Attentionなどの最適化されたカーネルを呼び出します。
+
+BetterTransformerは、テキスト、画像、音声モデルの単一GPUおよび複数GPUでの高速推論もサポートしています。
+
+
+Flash Attentionは、fp16またはbf16 dtypeを使用しているモデルにのみ使用できます。BetterTransformerを使用する前に、モデルを適切なdtypeにキャストしてください。
+
+
+
+### Decoder models
+
+テキストモデル、特にデコーダーベースのモデル(GPT、T5、Llamaなど)の場合、BetterTransformer APIはすべての注意操作を[`torch.nn.functional.scaled_dot_product_attention`オペレーター](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention)(SDPA)を使用するように変換します。これはPyTorch 2.0以降でのみ使用可能です。
+
+モデルをBetterTransformerに変換するには:
+
+```python
+from transformers import AutoModelForCausalLM
+
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-350m")
+# convert the model to BetterTransformer
+model.to_bettertransformer()
+
+# Use it for training or inference
+```
+
+SDPAは、ハードウェアや問題のサイズなどの特定の設定で[Flash Attention](https://arxiv.org/abs/2205.14135)カーネルを呼び出すこともできます。Flash Attentionを有効にするか、特定の設定(ハードウェア、問題のサイズ)で利用可能かを確認するには、[`torch.nn.kernel.sdpa_kernel`](https://pytorch.org/docs/stable/generated/torch.nn.attention.sdpa_kernel.html)をコンテキストマネージャとして使用します。
+
+
+```diff
+import torch
++ from torch.nn.attention import SDPBackend, sdpa_kernel
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-350m")
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-350m").to("cuda")
+# convert the model to BetterTransformer
+model.to_bettertransformer()
+
+input_text = "Hello my dog is cute and"
+inputs = tokenizer(input_text, return_tensors="pt").to("cuda")
+
++ with sdpa_kernel(SDPBackend.FLASH_ATTENTION):
+ outputs = model.generate(**inputs)
+
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+もしトレースバックで次のようなエラーメッセージが表示された場合:
+
+
+```bash
+RuntimeError: No available kernel. Aborting execution.
+```
+
+当日、Flash Attentionのカバレッジが広範囲である可能性があるPyTorch Nightlyバージョンを試すようにお勧めします。
+
+```bash
+pip3 install -U --pre torch torchvision torchaudio --index-url https://download.pytorch.org/whl/nightly/cu118
+```
+
+[このブログ投稿](https://pytorch.org/blog/out-of-the-box-acceleration/)をチェックして、BetterTransformer + SDPA APIで可能なことについて詳しく学びましょう。
+
+### Encoder Models
+
+推論中のエンコーダーモデルでは、BetterTransformerはエンコーダーレイヤーのforward呼び出しを、エンコーダーレイヤーの[`torch.nn.TransformerEncoderLayer`](https://pytorch.org/docs/stable/generated/torch.nn.TransformerEncoderLayer.html)の相当するものにディスパッチします。これにより、エンコーダーレイヤーの高速実装が実行されます。
+
+`torch.nn.TransformerEncoderLayer`の高速実装はトレーニングをサポートしていないため、代わりに`torch.nn.functional.scaled_dot_product_attention`にディスパッチされます。これにより、ネストされたテンソルを活用しないFlash AttentionまたはMemory-Efficient Attentionの融合カーネルを使用できます。
+
+BetterTransformerのパフォーマンスの詳細については、この[ブログ投稿](https://medium.com/pytorch/bettertransformer-out-of-the-box-performance-for-huggingface-transformers-3fbe27d50ab2)をご覧いただけます。また、エンコーダーモデル用のBetterTransformerについては、この[ブログ](https://pytorch.org/blog/a-better-transformer-for-fast-transformer-encoder-inference/)で詳しく学ぶことができます。
+
+
+## Advanced usage: mixing FP4 (or Int8) and BetterTransformer
+
+モデルの最良のパフォーマンスを得るために、上記で説明した異なる方法を組み合わせることができます。例えば、FP4ミックスプレシジョン推論+Flash Attentionを使用したBetterTransformerを組み合わせることができます。
+
+
+```py
+import torch
+from torch.nn.attention import SDPBackend, sdpa_kernel
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.float16
+)
+
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-350m")
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-350m", quantization_config=quantization_config)
+
+input_text = "Hello my dog is cute and"
+inputs = tokenizer(input_text, return_tensors="pt").to("cuda")
+
+with sdpa_kernel(SDPBackend.FLASH_ATTENTION):
+ outputs = model.generate(**inputs)
+
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_infer_gpu_one.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_infer_gpu_one.md
new file mode 100644
index 0000000000000000000000000000000000000000..6a3dc5fa64a8527c14dcf1a238b2feb331923d3b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_infer_gpu_one.md
@@ -0,0 +1,443 @@
+
+
+# Efficient Inference on a Single GPU
+
+このガイドに加えて、[1つのGPUでのトレーニングガイド](perf_train_gpu_one)と[CPUでの推論ガイド](perf_infer_cpu)に関連する情報があります。
+
+## Flash Attention 2
+
+
+
+この機能は実験的であり、将来のバージョンで大幅に変更される可能性があります。たとえば、Flash Attention 2 APIは近い将来`BetterTransformer` APIに移行するかもしれません。
+
+
+
+Flash Attention 2は、トランスフォーマーベースのモデルのトレーニングと推論速度を大幅に高速化できます。Flash Attention 2は、Tri Dao氏によって[公式のFlash Attentionリポジトリ](https://github.com/Dao-AILab/flash-attention)で導入されました。Flash Attentionに関する科学論文は[こちら](https://arxiv.org/abs/2205.14135)で見ることができます。
+
+Flash Attention 2を正しくインストールするには、上記のリポジトリに記載されているインストールガイドに従ってください。
+
+以下のモデルに対してFlash Attention 2をネイティブサポートしています:
+
+- Llama
+- Falcon
+
+さらに多くのモデルにFlash Attention 2のサポートを追加することをGitHubで提案することもでき、変更を統合するためにプルリクエストを開くこともできます。サポートされているモデルは、パディングトークンを使用してトレーニングを含む、推論とトレーニングに使用できます(現在の`BetterTransformer` APIではサポートされていない)。
+
+
+
+Flash Attention 2は、モデルのdtypeが`fp16`または`bf16`の場合にのみ使用でき、NVIDIA-GPUデバイスでのみ実行されます。この機能を使用する前に、モデルを適切なdtypeにキャストし、サポートされているデバイスにロードしてください。
+
+
+
+### Quick usage
+
+モデルでFlash Attention 2を有効にするには、`from_pretrained`の引数に`attn_implementation="flash_attention_2"`を追加します。
+
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, LlamaForCausalLM
+
+model_id = "tiiuae/falcon-7b"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+
+model = AutoModelForCausalLM.from_pretrained(
+ model_id,
+ torch_dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+)
+```
+
+こちらは、生成または微調整のために使用するテキストです。
+
+### Expected speedups
+
+特に長いシーケンスに対して、微調整と推論の際には、かなりの高速化が期待できます。ただし、Flash Attentionはパディングトークンを使用してアテンションスコアを計算しないため、シーケンスにパディングトークンが含まれる場合、バッチ推論においてアテンションスコアを手動でパッド/アンパッドする必要があり、パディングトークンを含むバッチ生成の大幅な遅延が発生します。
+
+これを克服するために、トレーニング中にシーケンスにパディングトークンを使用せずにFlash Attentionを使用する必要があります(たとえば、データセットをパックすることにより、シーケンスを最大シーケンス長に達するまで連結することなど)。ここに[例](https://github.com/huggingface/transformers/blob/main/examples/pytorch/language-modeling/run_clm.py#L516)が提供されています。
+
+以下は、パディングトークンのない場合に、シーケンス長が4096の[tiiuae/falcon-7b](https://hf.co/tiiuae/falcon-7b)に対する単純なフォワードパスの予想される高速化です。さまざまなバッチサイズが示されています:
+
+
+
+
+
+
+
+
+
+
+
+Flash Attentionは、fp16またはbf16のdtypeを使用するモデルにのみ使用できます。BetterTransformerを使用する前に、モデルを適切なdtypeにキャストしてください。
+
+
+
+### Encoder models
+
+PyTorchネイティブの[`nn.MultiHeadAttention`](https://pytorch.org/blog/a-better-transformer-for-fast-transformer-encoder-inference/)アテンション高速パス、BetterTransformerと呼ばれるものは、[🤗 Optimumライブラリ](https://huggingface.co/docs/optimum/bettertransformer/overview)の統合を通じてTransformersと一緒に使用できます。
+
+PyTorchのアテンション高速パスを使用すると、カーネルフュージョンと[ネストされたテンソル](https://pytorch.org/docs/stable/nested.html)の使用により、推論を高速化できます。詳細なベンチマーク情報は[このブログ記事](https://medium.com/pytorch/bettertransformer-out-of-the-box-performance-for-huggingface-transformers-3fbe27d50ab2)にあります。
+
+[`optimum`](https://github.com/huggingface/optimum)パッケージをインストールした後、推論中にBetter Transformerを使用するには、関連する内部モジュールを呼び出すことで置き換える必要があります[`~PreTrainedModel.to_bettertransformer`]:
+
+
+```python
+model = model.to_bettertransformer()
+```
+
+メソッド [`~PreTrainedModel.reverse_bettertransformer`] は、モデルを保存する前に使用すべきで、標準のトランスフォーマーモデリングを使用するためのものです:
+
+```python
+model = model.reverse_bettertransformer()
+model.save_pretrained("saved_model")
+```
+
+BetterTransformer APIを使ったエンコーダーモデルの可能性について詳しく知るには、[このブログポスト](https://medium.com/pytorch/bettertransformer-out-of-the-box-performance-for-huggingface-transformers-3fbe27d50ab2)をご覧ください。
+
+### Decoder models
+
+テキストモデル、特にデコーダーベースのモデル(GPT、T5、Llamaなど)にとって、BetterTransformer APIはすべての注意操作を[`torch.nn.functional.scaled_dot_product_attention`オペレーター](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention)(SDPA)を使用するように変換します。このオペレーターはPyTorch 2.0以降でのみ利用可能です。
+
+モデルをBetterTransformerに変換するには、以下の手順を実行してください:
+
+```python
+from transformers import AutoModelForCausalLM
+
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-350m")
+# convert the model to BetterTransformer
+model.to_bettertransformer()
+
+# Use it for training or inference
+```
+
+SDPAは、ハードウェアや問題のサイズに応じて[Flash Attention](https://arxiv.org/abs/2205.14135)カーネルを使用することもできます。Flash Attentionを有効にするか、特定の設定(ハードウェア、問題サイズ)で使用可能かどうかを確認するには、[`torch.nn.attention.sdpa_kernel`](https://pytorch.org/docs/stable/generated/torch.nn.attention.sdpa_kernel.html)をコンテキストマネージャとして使用します。
+
+
+```diff
+import torch
++ from torch.nn.attention import SDPBackend, sdpa_kernel
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-350m")
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-350m", torch_dtype=torch.float16).to("cuda")
+# convert the model to BetterTransformer
+model.to_bettertransformer()
+
+input_text = "Hello my dog is cute and"
+inputs = tokenizer(input_text, return_tensors="pt").to("cuda")
+
++ with sdpa_kernel(SDPBackend.FLASH_ATTENTION):
+ outputs = model.generate(**inputs)
+
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+もしトレースバックにバグが表示された場合
+
+```bash
+RuntimeError: No available kernel. Aborting execution.
+```
+
+Flash Attention の広範なカバレッジを持つかもしれない PyTorch のナイトリーバージョンを試してみることをお勧めします。
+
+```bash
+pip3 install -U --pre torch torchvision torchaudio --index-url https://download.pytorch.org/whl/nightly/cu118
+```
+
+Or make sure your model is correctly casted in float16 or bfloat16
+
+モデルが正しくfloat16またはbfloat16にキャストされていることを確認してください。
+
+Have a look at [this detailed blogpost](https://pytorch.org/blog/out-of-the-box-acceleration/) to read more about what is possible to do with `BetterTransformer` + SDPA API.
+
+`BetterTransformer` + SDPA APIを使用して何が可能かについて詳しく読むには、[この詳細なブログポスト](https://pytorch.org/blog/out-of-the-box-acceleration/)をご覧ください。
+
+## `bitsandbytes` integration for FP4 mixed-precision inference
+
+FP4混合精度推論のための`bitsandbytes`統合
+
+You can install `bitsandbytes` and benefit from easy model compression on GPUs. Using FP4 quantization you can expect to reduce up to 8x the model size compared to its native full precision version. Check out below how to get started.
+
+`bitsandbytes`をインストールし、GPUで簡単なモデルの圧縮を利用できます。FP4量子化を使用すると、ネイティブのフルプレシジョンバージョンと比較してモデルサイズを最大8倍削減できることが期待できます。以下を確認して、どのように始めるかをご覧ください。
+
+
+
+Note that this feature can also be used in a multi GPU setup.
+
+この機能は、マルチGPUセットアップでも使用できることに注意してください。
+
+
+
+### Requirements [[requirements-for-fp4-mixedprecision-inference]]
+
+- Latest `bitsandbytes` library
+`pip install bitsandbytes>=0.39.0`
+
+- Install latest `accelerate` from source
+`pip install git+https://github.com/huggingface/accelerate.git`
+
+- Install latest `transformers` from source
+`pip install git+https://github.com/huggingface/transformers.git`
+
+
+### Running FP4 models - single GPU setup - Quickstart
+
+以下のコードを実行することで、簡単に単一のGPUでFP4モデルを実行できます:
+
+
+```py
+from transformers import AutoModelForCausalLM
+
+model_name = "bigscience/bloom-2b5"
+model_4bit = AutoModelForCausalLM.from_pretrained(model_name, device_map="auto", load_in_4bit=True)
+```
+
+注意: `device_map`はオプションですが、推論時に `device_map = 'auto'` を設定することが推奨されています。これにより、利用可能なリソースに効率的にモデルがディスパッチされます。
+
+### Running FP4 models - multi GPU setup
+
+混合4ビットモデルを複数のGPUにロードする方法は、単一GPUセットアップと同じです(単一GPUセットアップと同じコマンドです):
+
+```py
+model_name = "bigscience/bloom-2b5"
+model_4bit = AutoModelForCausalLM.from_pretrained(model_name, device_map="auto", load_in_4bit=True)
+```
+
+しかし、`accelerate`を使用して、各GPUに割り当てるGPU RAMを制御することができます。以下のように、`max_memory`引数を使用します:
+
+
+```py
+max_memory_mapping = {0: "600MB", 1: "1GB"}
+model_name = "bigscience/bloom-3b"
+model_4bit = AutoModelForCausalLM.from_pretrained(
+ model_name, device_map="auto", load_in_4bit=True, max_memory=max_memory_mapping
+)
+```
+
+この例では、最初のGPUは600MBのメモリを使用し、2番目のGPUは1GBを使用します。
+
+### Advanced usage
+
+このメソッドのさらなる高度な使用法については、[量子化](main_classes/quantization)のドキュメンテーションページをご覧ください。
+
+## `bitsandbytes` integration for Int8 mixed-precision matrix decomposition
+
+
+
+この機能は、マルチGPU環境でも使用できます。
+
+
+
+論文[`LLM.int8():スケーラブルなTransformer向けの8ビット行列乗算`](https://arxiv.org/abs/2208.07339)によれば、Hugging Face統合がHub内のすべてのモデルでわずか数行のコードでサポートされています。このメソッドは、半精度(`float16`および`bfloat16`)の重みの場合に`nn.Linear`サイズを2倍、単精度(`float32`)の重みの場合は4倍に縮小し、外れ値に対してほとんど影響を与えません。
+
+
+
+Int8混合精度行列分解は、行列乗算を2つのストリームに分割することによって動作します:(1) システマティックな特徴外れ値ストリームがfp16で行列乗算(0.01%)、(2) int8行列乗算の通常のストリーム(99.9%)。この方法を使用すると、非常に大きなモデルに対して予測の劣化なしにint8推論が可能です。
+このメソッドの詳細については、[論文](https://arxiv.org/abs/2208.07339)または[この統合に関するブログ記事](https://huggingface.co/blog/hf-bitsandbytes-integration)をご確認ください。
+
+
+
+なお、この機能を使用するにはGPUが必要であり、カーネルはGPU専用にコンパイルされている必要があります。この機能を使用する前に、モデルの1/4(またはハーフ精度の重みの場合は1/2)を保存するのに十分なGPUメモリがあることを確認してください。
+このモジュールを使用する際のヘルプに関する詳細は、以下のノートをご覧いただくか、[Google Colabのデモ](#colab-demos)をご覧ください。
+
+### Requirements [[requirements-for-int8-mixedprecision-matrix-decomposition]]
+
+- `bitsandbytes<0.37.0`を使用する場合、NVIDIA GPUを使用していることを確認し、8ビットテンソルコアをサポートしていることを確認してください(Turing、Ampere、またはそれ以降のアーキテクチャー、例:T4、RTX20s RTX30s、A40-A100など)。`bitsandbytes>=0.37.0`の場合、すべてのGPUがサポートされるはずです。
+- 正しいバージョンの`bitsandbytes`をインストールするには、次のコマンドを実行してください:
+`pip install bitsandbytes>=0.31.5`
+- `accelerate`をインストールします:
+`pip install accelerate>=0.12.0`
+
+
+### Running mixed-Int8 models - single GPU setup
+
+必要なライブラリをインストールした後、ミックス 8 ビットモデルを読み込む方法は次の通りです:
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+model_name = "bigscience/bloom-2b5"
+model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+
+以下はシンプルな例です:
+
+* `pipeline()` 関数の代わりに、モデルの `generate()` メソッドを使用することをお勧めします。`pipeline()` 関数を使用して推論することは可能ですが、混合8ビットモデルに最適化されておらず、`generate()` メソッドを使用するよりも遅くなります。また、一部のサンプリング戦略(例:ヌクレウスサンプリング)は、`pipeline()` 関数では混合8ビットモデルではサポートされていません。
+* すべての入力をモデルと同じデバイスに配置してください。
+
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model_name = "bigscience/bloom-2b5"
+tokenizer = AutoTokenizer.from_pretrained(model_name)
+model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+
+prompt = "Hello, my llama is cute"
+inputs = tokenizer(prompt, return_tensors="pt").to("cuda")
+generated_ids = model.generate(**inputs)
+outputs = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+```
+
+### Running mixed-int8 models - multi GPU setup
+
+複数のGPUに混合8ビットモデルをロードする方法は、次の通りです(シングルGPUセットアップと同じコマンドです):
+
+```py
+model_name = "bigscience/bloom-2b5"
+model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+
+`accelerate`を使用して各GPUに割り当てるGPU RAMを制御する際には、以下のように`max_memory`引数を使用します:
+
+
+```py
+max_memory_mapping = {0: "1GB", 1: "2GB"}
+model_name = "bigscience/bloom-3b"
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ model_name, device_map="auto", load_in_8bit=True, max_memory=max_memory_mapping
+)
+```
+
+In this example, the first GPU will use 1GB of memory and the second 2GB.
+
+### Colab demos
+
+この方法を使用すると、以前のGoogle Colabでは推論できなかったモデルに対して推論を行うことができます。以下は、Google Colabで8ビット量子化を使用してT5-11b(fp32で42GB)を実行するデモのリンクです:
+
+[](https://colab.research.google.com/drive/1YORPWx4okIHXnjW7MSAidXN29mPVNT7F?usp=sharing)
+
+また、BLOOM-3Bのデモもご覧いただけます:
+
+[](https://colab.research.google.com/drive/1qOjXfQIAULfKvZqwCen8-MoWKGdSatZ4?usp=sharing)
+
+## Advanced usage: mixing FP4 (or Int8) and BetterTransformer
+
+異なる方法を組み合わせて、モデルの最適なパフォーマンスを得ることができます。例えば、BetterTransformerを使用してFP4ミックスプレシジョン推論とフラッシュアテンションを組み合わせることができます。
+
+
+```py
+import torch
+from torch.nn.attention import SDPBackend, sdpa_kernel
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.float16
+)
+
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-350m")
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-350m", quantization_config=quantization_config)
+
+input_text = "Hello my dog is cute and"
+inputs = tokenizer(input_text, return_tensors="pt").to("cuda")
+
+with sdpa_kernel(SDPBackend.FLASH_ATTENTION):
+ outputs = model.generate(**inputs)
+
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_infer_special.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_infer_special.md
new file mode 100644
index 0000000000000000000000000000000000000000..a5102590a0504cf20b9bbdc31312c6ff200ec9e7
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_infer_special.md
@@ -0,0 +1,18 @@
+
+
+# Inference on Specialized Hardware
+
+こちらのドキュメントは、専用のハードウェアでの推論方法についての情報がまもなく提供されます。その間に、CPUでの推論に関するガイドをご覧いただけます。[the guide for inference on CPUs](perf_infer_cpu).
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_torch_compile.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_torch_compile.md
new file mode 100644
index 0000000000000000000000000000000000000000..c2cc505b286228c2cdd62a8395b11f79ee3a88f2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_torch_compile.md
@@ -0,0 +1,359 @@
+
+
+# Optimize inference using torch.compile()
+
+このガイドは、[`torch.compile()`](https://pytorch.org/tutorials/intermediate/torch_compile_tutorial.html) を使用した推論速度の向上に関するベンチマークを提供することを目的としています。これは、[🤗 Transformers のコンピュータビジョンモデル](https://huggingface.co/models?pipeline_tag=image-classification&library=transformers&sort=trending)向けのものです。
+
+## Benefits of torch.compile
+
+`torch.compile()`の利点
+モデルとGPUによっては、torch.compile()は推論時に最大30%の高速化を実現します。 `torch.compile()`を使用するには、バージョン2.0以上のtorchをインストールするだけです。
+
+モデルのコンパイルには時間がかかるため、毎回推論するのではなく、モデルを1度だけコンパイルする場合に役立ちます。
+任意のコンピュータビジョンモデルをコンパイルするには、以下のようにモデルに`torch.compile()`を呼び出します:
+
+```diff
+from transformers import AutoModelForImageClassification
+
+model = AutoModelForImageClassification.from_pretrained(MODEL_ID).to("cuda")
++ model = torch.compile(model)
+```
+
+`compile()` は、コンパイルに関する異なるモードを備えており、基本的にはコンパイル時間と推論のオーバーヘッドが異なります。`max-autotune` は `reduce-overhead` よりも時間がかかりますが、推論速度が速くなります。デフォルトモードはコンパイルにおいては最速ですが、推論時間においては `reduce-overhead` に比べて効率が良くありません。このガイドでは、デフォルトモードを使用しました。詳細については、[こちら](https://pytorch.org/get-started/pytorch-2.0/#user-experience) を参照してください。
+
+`torch` バージョン 2.0.1 で異なるコンピュータビジョンモデル、タスク、ハードウェアの種類、およびバッチサイズを使用して `torch.compile` をベンチマークしました。
+
+## Benchmarking code
+
+以下に、各タスクのベンチマークコードを示します。推論前にGPUをウォームアップし、毎回同じ画像を使用して300回の推論の平均時間を取得します。
+
+### Image Classification with ViT
+
+```python
+from PIL import Image
+import requests
+import numpy as np
+from transformers import AutoImageProcessor, AutoModelForImageClassification
+
+url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+image = Image.open(requests.get(url, stream=True).raw)
+
+processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+model = AutoModelForImageClassification.from_pretrained("google/vit-base-patch16-224").to("cuda")
+model = torch.compile(model)
+
+processed_input = processor(image, return_tensors='pt').to(device="cuda")
+
+with torch.no_grad():
+ _ = model(**processed_input)
+```
+
+#### Object Detection with DETR
+
+```python
+from transformers import AutoImageProcessor, AutoModelForObjectDetection
+
+processor = AutoImageProcessor.from_pretrained("facebook/detr-resnet-50")
+model = AutoModelForObjectDetection.from_pretrained("facebook/detr-resnet-50").to("cuda")
+model = torch.compile(model)
+
+texts = ["a photo of a cat", "a photo of a dog"]
+inputs = processor(text=texts, images=image, return_tensors="pt").to("cuda")
+
+with torch.no_grad():
+ _ = model(**inputs)
+```
+
+#### Image Segmentation with Segformer
+
+```python
+from transformers import SegformerImageProcessor, SegformerForSemanticSegmentation
+
+processor = SegformerImageProcessor.from_pretrained("nvidia/segformer-b0-finetuned-ade-512-512")
+model = SegformerForSemanticSegmentation.from_pretrained("nvidia/segformer-b0-finetuned-ade-512-512").to("cuda")
+model = torch.compile(model)
+seg_inputs = processor(images=image, return_tensors="pt").to("cuda")
+
+with torch.no_grad():
+ _ = model(**seg_inputs)
+```
+
+以下は、私たちがベンチマークを行ったモデルのリストです。
+
+
+**Image Classification**
+- [google/vit-base-patch16-224](https://huggingface.co/google/vit-base-patch16-224)
+- [microsoft/beit-base-patch16-224-pt22k-ft22k](https://huggingface.co/microsoft/beit-base-patch16-224-pt22k-ft22k)
+- [facebook/convnext-large-224](https://huggingface.co/facebook/convnext-large-224)
+- [microsoft/resnet-50](https://huggingface.co/)
+
+**Image Segmentation**
+- [nvidia/segformer-b0-finetuned-ade-512-512](https://huggingface.co/nvidia/segformer-b0-finetuned-ade-512-512)
+- [facebook/mask2former-swin-tiny-coco-panoptic](https://huggingface.co/facebook/mask2former-swin-tiny-coco-panoptic)
+- [facebook/maskformer-swin-base-ade](https://huggingface.co/facebook/maskformer-swin-base-ade)
+- [google/deeplabv3_mobilenet_v2_1.0_513](https://huggingface.co/google/deeplabv3_mobilenet_v2_1.0_513)
+
+**Object Detection**
+- [google/owlvit-base-patch32](https://huggingface.co/google/owlvit-base-patch32)
+- [facebook/detr-resnet-101](https://huggingface.co/facebook/detr-resnet-101)
+- [microsoft/conditional-detr-resnet-50](https://huggingface.co/microsoft/conditional-detr-resnet-50)
+
+
+以下は、`torch.compile()`を使用した場合と使用しない場合の推論時間の可視化と、異なるハードウェアとバッチサイズの各モデルに対するパフォーマンス向上の割合です。
+
+
+
+
+
+
+
+
+
+
+
+
-f https://developer.intel.com/ipex-whl-stable-cpu
+```
+
+[IPEXのインストール方法](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/installation.html)について、さらなるアプローチを確認してください。
+
+### Trainerでの使用方法
+TrainerでIPEXの自動混合精度を有効にするには、ユーザーはトレーニングコマンド引数に `use_ipex`、`bf16`、および `no_cuda` を追加する必要があります。
+
+[Transformersの質問応答](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)のユースケースを例に説明します。
+
+- CPU上でBF16自動混合精度を使用してIPEXでトレーニングを行う場合:
+ python run_qa.py \
+--model_name_or_path google-bert/bert-base-uncased \
+--dataset_name squad \
+--do_train \
+--do_eval \
+--per_device_train_batch_size 12 \
+--learning_rate 3e-5 \
+--num_train_epochs 2 \
+--max_seq_length 384 \
+--doc_stride 128 \
+--output_dir /tmp/debug_squad/ \
+--use_ipex \
+--bf16 --no_cuda
+
+### Practice example
+
+Blog: [Accelerating PyTorch Transformers with Intel Sapphire Rapids](https://huggingface.co/blog/intel-sapphire-rapids)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_cpu_many.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_cpu_many.md
new file mode 100644
index 0000000000000000000000000000000000000000..26da32f577251ff437ab0978ad4083e01ba17781
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_cpu_many.md
@@ -0,0 +1,151 @@
+
+
+
+# Efficient Training on Multiple CPUs
+
+1つのCPUでのトレーニングが遅すぎる場合、複数のCPUを使用できます。このガイドは、PyTorchベースのDDPを使用した分散CPUトレーニングに焦点を当てています。
+
+## Intel® oneCCL Bindings for PyTorch
+
+[Intel® oneCCL](https://github.com/oneapi-src/oneCCL)(集合通信ライブラリ)は、allreduce、allgather、alltoallなどの収集通信を実装した効率的な分散ディープラーニングトレーニング用のライブラリです。oneCCLの詳細については、[oneCCLドキュメント](https://spec.oneapi.com/versions/latest/elements/oneCCL/source/index.html)と[oneCCL仕様](https://spec.oneapi.com/versions/latest/elements/oneCCL/source/index.html)を参照してください。
+
+モジュール`oneccl_bindings_for_pytorch`(バージョン1.12以前は`torch_ccl`)は、PyTorch C10D ProcessGroup APIを実装し、外部のProcessGroupとして動的にロードでき、現在はLinuxプラットフォームでのみ動作します。
+
+[torch-ccl](https://github.com/intel/torch-ccl)の詳細情報を確認してください。
+
+### Intel® oneCCL Bindings for PyTorch installation:
+
+Wheelファイルは、以下のPythonバージョン用に利用可能です:
+
+| Extension Version | Python 3.6 | Python 3.7 | Python 3.8 | Python 3.9 | Python 3.10 |
+| :---------------: | :--------: | :--------: | :--------: | :--------: | :---------: |
+| 1.13.0 | | √ | √ | √ | √ |
+| 1.12.100 | | √ | √ | √ | √ |
+| 1.12.0 | | √ | √ | √ | √ |
+| 1.11.0 | | √ | √ | √ | √ |
+| 1.10.0 | √ | √ | √ | √ | |
+
+```bash
+pip install oneccl_bind_pt=={pytorch_version} -f https://developer.intel.com/ipex-whl-stable-cpu
+```
+
+where `{pytorch_version}` should be your PyTorch version, for instance 1.13.0.
+Check more approaches for [oneccl_bind_pt installation](https://github.com/intel/torch-ccl).
+Versions of oneCCL and PyTorch must match.
+
+
+
+oneccl_bindings_for_pytorch 1.12.0 prebuilt wheel does not work with PyTorch 1.12.1 (it is for PyTorch 1.12.0)
+PyTorch 1.12.1 should work with oneccl_bindings_for_pytorch 1.12.100
+
+
+
+`{pytorch_version}` は、あなたのPyTorchのバージョン(例:1.13.0)に置き換える必要があります。重要なのは、oneCCLとPyTorchのバージョンが一致していることです。[oneccl_bind_ptのインストール](https://github.com/intel/torch-ccl)に関するさらなるアプローチを確認できます。
+
+
+
+`oneccl_bindings_for_pytorch`の1.12.0プリビルトホイールはPyTorch 1.12.1と互換性がありません(これはPyTorch 1.12.0用です)。PyTorch 1.12.1を使用する場合は、`oneccl_bindings_for_pytorch`バージョン1.12.100を使用する必要があります。
+
+
+
+## Intel® MPI library
+
+
+この基準ベースのMPI実装を使用して、Intel®アーキテクチャ上で柔軟で効率的、スケーラブルなクラスタメッセージングを提供します。このコンポーネントは、Intel® oneAPI HPC Toolkitの一部です。
+
+oneccl_bindings_for_pytorchはMPIツールセットと一緒にインストールされます。使用する前に環境をソース化する必要があります。
+
+
+for Intel® oneCCL >= 1.12.0
+```bash
+oneccl_bindings_for_pytorch_path=$(python -c "from oneccl_bindings_for_pytorch import cwd; print(cwd)")
+source $oneccl_bindings_for_pytorch_path/env/setvars.sh
+```
+
+for Intel® oneCCL whose version < 1.12.0
+```bash
+torch_ccl_path=$(python -c "import torch; import torch_ccl; import os; print(os.path.abspath(os.path.dirname(torch_ccl.__file__)))")
+source $torch_ccl_path/env/setvars.sh
+```
+
+#### IPEX installation:
+
+IPEXは、Float32およびBFloat16の両方でCPUトレーニングのパフォーマンス最適化を提供します。詳細は[こちらのシングルCPUセクション](./perf_train_cpu)をご参照ください。
+
+以下の「トレーナーでの使用」は、Intel® MPIライブラリでmpirunを使用する例を示しています。
+
+## Usage in Trainer
+トレーナーでのマルチCPU分散トレーニングを有効にするために、ユーザーはコマンド引数に **`--ddp_backend ccl`** を追加する必要があります。
+
+例を見てみましょう。[質問応答の例](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)
+
+以下のコマンドは、1つのXeonノードで2つのプロセスを使用してトレーニングを有効にします。1つのプロセスが1つのソケットで実行されます。OMP_NUM_THREADS/CCL_WORKER_COUNT変数は、最適なパフォーマンスを調整するために調整できます。
+
+
+```shell script
+ export CCL_WORKER_COUNT=1
+ export MASTER_ADDR=127.0.0.1
+ mpirun -n 2 -genv OMP_NUM_THREADS=23 \
+ python3 run_qa.py \
+ --model_name_or_path google-bert/bert-large-uncased \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --per_device_train_batch_size 12 \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir /tmp/debug_squad/ \
+ --no_cuda \
+ --ddp_backend ccl \
+ --use_ipex
+```
+
+以下のコマンドは、2つのXeonプロセッサ(node0とnode1、node0をメインプロセスとして使用)で合計4つのプロセスを使用してトレーニングを有効にします。ppn(ノードごとのプロセス数)は2に設定され、1つのソケットごとに1つのプロセスが実行されます。最適なパフォーマンスを得るために、OMP_NUM_THREADS/CCL_WORKER_COUNT変数を調整できます。
+
+node0では、各ノードのIPアドレスを含む構成ファイルを作成し、その構成ファイルのパスを引数として渡す必要があります。
+
+```shell script
+ cat hostfile
+ xxx.xxx.xxx.xxx #node0 ip
+ xxx.xxx.xxx.xxx #node1 ip
+```
+
+ノード0で次のコマンドを実行すると、ノード0とノード1で**4DDP**がBF16自動混合精度で有効になります。
+
+
+```shell script
+ export CCL_WORKER_COUNT=1
+ export MASTER_ADDR=xxx.xxx.xxx.xxx #node0 ip
+ mpirun -f hostfile -n 4 -ppn 2 \
+ -genv OMP_NUM_THREADS=23 \
+ python3 run_qa.py \
+ --model_name_or_path google-bert/bert-large-uncased \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --per_device_train_batch_size 12 \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir /tmp/debug_squad/ \
+ --no_cuda \
+ --ddp_backend ccl \
+ --use_ipex \
+ --bf16
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_gpu_many.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_gpu_many.md
new file mode 100644
index 0000000000000000000000000000000000000000..d85165d0c547a06661cc521b9720df78619b22bb
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_gpu_many.md
@@ -0,0 +1,529 @@
+
+
+# Efficient Training on Multiple GPUs
+
+単一のGPUでのトレーニングが遅すぎる場合や、モデルの重みが単一のGPUのメモリに収まらない場合、複数のGPUを使用したセットアップが必要となります。単一のGPUから複数のGPUへの切り替えには、ワークロードを分散するためのある種の並列処理が必要です。データ、テンソル、またはパイプラインの並列処理など、さまざまな並列処理技術があります。ただし、すべてに適した一つの解決策は存在せず、最適な設定は使用するハードウェアに依存します。この記事は、おそらく他のフレームワークにも適用される主要な概念に焦点を当てつつ、PyTorchベースの実装に焦点を当てています。
+
+
+
+**注意**: [単一GPUセクション](perf_train_gpu_one) で紹介された多くの戦略(混合精度トレーニングや勾配蓄積など)は一般的であり、モデルのトレーニングに一般的に適用されます。したがって、マルチGPUやCPUトレーニングなどの次のセクションに入る前に、それを確認してください。
+
+
+
+まず、さまざまな1D並列処理技術とその利点および欠点について詳しく説明し、それらを2Dおよび3D並列処理に組み合わせてさらに高速なトレーニングを実現し、より大きなモデルをサポートする方法を検討します。さまざまな他の強力な代替手法も紹介されます。
+
+## Concepts
+
+以下は、この文書で後で詳しく説明される主要な概念の簡単な説明です。
+
+1. **DataParallel (DP)** - 同じセットアップが複数回複製され、各セットアップにデータのスライスが供給されます。処理は並行して行われ、各セットアップはトレーニングステップの最後に同期されます。
+2. **TensorParallel (TP)** - 各テンソルは複数のチャンクに分割され、単一のGPUにテンソル全体が存在するのではなく、テンソルの各シャードが指定されたGPUに存在します。処理中に、各シャードは別々に並行して処理され、異なるGPUで同期され、ステップの最後に結果が同期されます。これは水平並列処理と呼ばれるもので、分割は水平レベルで行われます。
+3. **PipelineParallel (PP)** - モデルは垂直(レイヤーレベル)に複数のGPUに分割され、モデルの単一または複数のレイヤーが単一のGPUに配置されます。各GPUはパイプラインの異なるステージを並行して処理し、バッチの小さなチャンクで作業します。
+4. **Zero Redundancy Optimizer (ZeRO)** - TPといくらか似たようなテンソルのシャーディングを実行しますが、前向きまたは後向きの計算のためにテンソル全体が再構築されるため、モデルを変更する必要はありません。また、GPUメモリが制限されている場合に補償するためのさまざまなオフロード技術をサポートします。
+5. **Sharded DDP** - Sharded DDPは、さまざまなZeRO実装で使用される基本的なZeROコンセプトの別名です。
+
+各コンセプトの詳細に深入りする前に、大規模なインフラストラクチャで大規模なモデルをトレーニングする際の大まかな決定プロセスを見てみましょう。
+
+## Scalability Strategy
+
+**⇨ シングルノード / マルチGPU**
+* モデルが単一のGPUに収まる場合:
+
+ 1. DDP - 分散データ並列
+ 2. ZeRO - 状況と使用される構成に応じて速いかどうかが異なります
+
+* モデルが単一のGPUに収まらない場合:
+
+ 1. PP
+ 2. ZeRO
+ 3. TP
+
+ 非常に高速なノード内接続(NVLINKまたはNVSwitchなど)があれば、これらの3つはほぼ同じ速度になるはずで、これらがない場合、PPはTPまたはZeROよりも速くなります。TPの程度も差を生じるかもしれません。特定のセットアップでの勝者を見つけるために実験することが最善です。
+
+ TPはほとんどの場合、単一ノード内で使用されます。つまり、TPサイズ <= ノードごとのGPU数です。
+
+* 最大のレイヤーが単一のGPUに収まらない場合:
+
+ 1. ZeROを使用しない場合 - TPを使用する必要があります。PP単独では収まらないでしょう。
+ 2. ZeROを使用する場合 - "シングルGPU"のエントリと同じものを参照してください
+
+**⇨ マルチノード / マルチGPU**
+
+* ノード間の高速接続がある場合:
+
+ 1. ZeRO - モデルへのほとんどの変更が不要です
+ 2. PP+TP+DP - 通信が少なく、モデルへの大規模な変更が必要です
+
+* ノード間の接続が遅く、GPUメモリがまだ不足している場合:
+
+ 1. DP+PP+TP+ZeRO-1
+
+## Data Parallelism
+
+2つのGPUを持つほとんどのユーザーは、`DataParallel`(DP)と`DistributedDataParallel`(DDP)によって提供されるトレーニング速度の向上をすでに享受しています。これらはほぼ自明に使用できるPyTorchの組み込み機能です。一般的に、すべてのモデルで動作するDDPを使用することをお勧めします。DPは一部のモデルで失敗する可能性があるためです。[PyTorchのドキュメンテーション](https://pytorch.org/docs/master/generated/torch.nn.DataParallel.html)自体もDDPの使用を推奨しています。
+
+### DP vs DDP
+
+`DistributedDataParallel`(DDP)は通常、`DataParallel`(DP)よりも高速ですが、常にそうとは限りません:
+* DPはPythonスレッドベースですが、DDPはマルチプロセスベースです。そのため、GIL(Global Interpreter Lock)などのPythonスレッドの制約がないためです。
+* 一方、GPUカード間の遅い相互接続性は、DDPの場合に実際には遅い結果をもたらす可能性があります。
+
+以下は、2つのモード間のGPU間通信の主な違いです:
+
+[DDP](https://pytorch.org/docs/master/notes/ddp.html):
+
+- 開始時、メインプロセスはモデルをGPU 0から他のGPUに複製します。
+- それから各バッチごとに:
+ 1. 各GPUは各自のミニバッチのデータを直接消費します。
+ 2. `backward`中、ローカル勾配が準備できると、それらはすべてのプロセスで平均化されます。
+
+[DP](https://pytorch.org/docs/master/generated/torch.nn.DataParallel.html):
+
+各バッチごとに:
+ 1. GPU 0はデータバッチを読み取り、それから各GPUにミニバッチを送信します。
+ 2. GPU 0から各GPUに最新のモデルを複製します。
+ 3. `forward`を実行し、各GPUからGPU 0に出力を送信し、損失を計算します。
+ 4. GPU 0からすべてのGPUに損失を分散し、`backward`を実行します。
+ 5. 各GPUからGPU 0に勾配を送信し、それらを平均化します。
+
+DDPはバッチごとに行う通信は勾配の送信のみであり、一方、DPはバッチごとに5つの異なるデータ交換を行います。
+
+DPはプロセス内でデータをPythonスレッドを介してコピーしますが、DDPは[torch.distributed](https://pytorch.org/docs/master/distributed.html)を介してデータをコピーします。
+
+DPではGPU 0は他のGPUよりもはるかに多くの作業を行うため、GPUの未使用率が高くなります。
+
+DDPは複数のマシン間で使用できますが、DPの場合はそうではありません。
+
+DPとDDPの他にも違いがありますが、この議論には関係ありません。
+
+これら2つのモードを深く理解したい場合、この[記事](https://www.telesens.co/2019/04/04/distributed-data-parallel-training-using-pytorch-on-aws/)を強くお勧めします。素晴らしいダイアグラムを含み、さまざまなハードウェアでの複数のベンチマークとプロファイラの出力を示し、知っておく必要があるすべての微妙なニュアンスを説明しています。
+
+実際のベンチマークを見てみましょう:
+
+| Type | NVlink | Time |
+| :----- | ----- | ---: |
+| 2:DP | Y | 110s |
+| 2:DDP | Y | 101s |
+| 2:DDP | N | 131s |
+
+
+解析:
+
+ここで、DPはNVlinkを使用したDDPに比べて約10%遅く、NVlinkを使用しないDDPに比べて約15%高速であることが示されています。
+
+実際の違いは、各GPUが他のGPUと同期する必要があるデータの量に依存します。同期するデータが多いほど、遅いリンクが合計の実行時間を遅くする可能性が高くなります。
+
+以下は完全なベンチマークコードと出力です:
+
+`NCCL_P2P_DISABLE=1`を使用して、対応するベンチマークでNVLink機能を無効にしました。
+
+
+```bash
+
+# DP
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 \
+python examples/pytorch/language-modeling/run_clm.py \
+--model_name_or_path openai-community/gpt2 --dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 \
+--do_train --output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 110.5948, 'train_samples_per_second': 1.808, 'epoch': 0.69}
+
+# DDP w/ NVlink
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 \
+torchrun --nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py \
+--model_name_or_path openai-community/gpt2 --dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 \
+--do_train --output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 101.9003, 'train_samples_per_second': 1.963, 'epoch': 0.69}
+
+# DDP w/o NVlink
+rm -r /tmp/test-clm; NCCL_P2P_DISABLE=1 CUDA_VISIBLE_DEVICES=0,1 \
+torchrun --nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py \
+--model_name_or_path openai-community/gpt2 --dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 \
+--do_train --output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 131.4367, 'train_samples_per_second': 1.522, 'epoch': 0.69}
+```
+
+ハードウェア: 2x TITAN RTX、各24GB + 2つのNVLink(`nvidia-smi topo -m`で `NV2`)
+
+ソフトウェア: `pytorch-1.8-to-be` + `cuda-11.0` / `transformers==4.3.0.dev0`
+
+## ZeRO Data Parallelism
+
+ZeROパワードデータ並列処理(ZeRO-DP)は、次の[ブログ投稿](https://www.microsoft.com/en-us/research/blog/zero-deepspeed-new-system-optimizations-enable-training-models-with-over-100-billion-parameters/)のダイアグラムで説明されています。
+
+
+これは理解が難しいかもしれませんが、実際にはこの概念は非常にシンプルです。これは通常の`DataParallel`(DP)ですが、完全なモデルパラメータ、勾配、およびオプティマイザの状態を複製する代わりに、各GPUはそれぞれのスライスのみを保存します。そして、実行時に、特定のレイヤーに必要な完全なレイヤーパラメータが必要な場合、すべてのGPUが同期して、お互いに不足している部分を提供します。それがすべてです。
+
+3つのレイヤーからなる単純なモデルを考えてみましょう。各レイヤーには3つのパラメータがあります:
+
+
+```
+La | Lb | Lc
+---|----|---
+a0 | b0 | c0
+a1 | b1 | c1
+a2 | b2 | c2
+```
+
+レイヤーLaには、重みa0、a1、およびa2があります。
+
+3つのGPUがある場合、Sharded DDP(= Zero-DP)はモデルを3つのGPUに次のように分割します:
+
+
+```
+GPU0:
+La | Lb | Lc
+---|----|---
+a0 | b0 | c0
+
+GPU1:
+La | Lb | Lc
+---|----|---
+a1 | b1 | c1
+
+GPU2:
+La | Lb | Lc
+---|----|---
+a2 | b2 | c2
+```
+
+これは、典型的なディープニューラルネットワーク(DNN)のダイアグラムを想像すると、テンソル並列処理と同様の水平スライスであるようなものです。垂直スライスは、異なるGPUに完全な層グループを配置する方法です。しかし、これは単なる出発点に過ぎません。
+
+これから、各GPUは通常のデータ並列処理(DP)と同様に、通常のミニバッチを受け取ります:
+
+```
+x0 => GPU0
+x1 => GPU1
+x2 => GPU2
+```
+
+最初に、入力データはレイヤーLaに適用されます。
+
+GPU0に焦点を当てましょう:x0は、その前向きパスを実行するためにa0、a1、a2のパラメータが必要ですが、GPU0にはa0しかありません。GPU1からa1を、GPU2からa2を受け取り、モデルの各部分をまとめます。
+
+同様に、GPU1はミニバッチx1を受け取り、a1しか持っていませんが、a0とa2のパラメータが必要です。これらはGPU0とGPU2から取得します。
+
+GPU2もx2を受け取ります。a0とa1はGPU0とGPU1から受け取り、a2とともに完全なテンソルを再構築します。
+
+3つのGPUは完全なテンソルを再構築し、前向き計算が行われます。
+
+計算が完了すると、不要になったデータは削除されます。計算中だけ使用され、再構築は事前にフェッチを使用して効率的に行われます。
+
+そして、このプロセス全体がレイヤーLb、次に前向きでLc、そして逆方向でLc -> Lb -> Laに対して繰り返されます。
+
+私にとって、これは効率的なグループでの重みの分散戦略のように聞こえます:
+
+1. 人Aはテントを持っています。
+2. 人Bはストーブを持っています。
+3. 人Cは斧を持っています。
+
+今、彼らは毎晩持っているものを共有し、他の人から持っていないものをもらい、朝には割り当てられたタイプのギアを詰めて旅を続けます。これがSharded DDP / Zero DPです。
+
+この戦略を、各人が独自のテント、ストーブ、斧を持って運ばなければならないシンプルな戦略と比較してみてください。これがPyTorchのDataParallel(DPおよびDDP)です。
+
+このトピックの文献を読む際に、以下の類義語に出会うかもしれません:Sharded、Partitioned。
+
+ZeROがモデルの重みを分割する方法に注意を払うと、これはテンソルパラレリズムと非常に似ているように見えます。これは後で議論される垂直モデルパラレリズムとは異なり、各レイヤーの重みをパーティション/シャーディングします。
+
+Implementations:
+
+- [DeepSpeed](https://www.deepspeed.ai/tutorials/zero/) ZeRO-DP stages 1+2+3
+- [`transformers` integration](main_classes/trainer#trainer-integrations)
+
+
+## Naive Model Parallelism (Vertical) and Pipeline Parallelism
+
+ナイーブモデルパラレリズム(MP)は、モデルの層を複数のGPUに分散させる方法です。このメカニズムは比較的単純で、希望する層を`.to()`メソッドを使用して特定のデバイスに切り替えるだけです。これにより、データがこれらの層を通過するたびに、データも層と同じデバイスに切り替えられ、残りの部分は変更されません。
+
+私たちはこれを「垂直MP」と呼びます。なぜなら、ほとんどのモデルがどのように描かれるかを思い出すと、層を垂直にスライスするからです。たとえば、以下の図は8層のモデルを示しています:
+
+
+```
+=================== ===================
+| 0 | 1 | 2 | 3 | | 4 | 5 | 6 | 7 |
+=================== ===================
+ gpu0 gpu1
+```
+
+我々は、モデルを垂直に2つに分割し、レイヤー0から3をGPU0に配置し、レイヤー4から7をGPU1に配置しました。
+
+データがレイヤー0から1、1から2、2から3に移動する間は通常のモデルと同じです。しかし、データがレイヤー3からレイヤー4に移動する必要がある場合、GPU0からGPU1への移動が発生し、通信のオーバーヘッドが発生します。参加しているGPUが同じコンピュートノード(例:同じ物理マシン)にある場合、このコピーは非常に高速ですが、異なるコンピュートノード(例:複数のマシン)にある場合、通信のオーバーヘッドは大幅に増加する可能性があります。
+
+その後、レイヤー4から5、6から7までは通常のモデルと同様に動作し、7番目のレイヤーが完了すると、データをしばしばレイヤー0に戻す必要があります(またはラベルを最後のレイヤーに送信します)。これで損失を計算し、オプティマイザが作業を開始できます。
+
+問題点:
+- 主な欠点、およびなぜこれを「単純な」MPと呼ぶのかは、1つを除いてすべてのGPUがどんな瞬間でもアイドル状態であることです。したがって、4つのGPUを使用する場合、単純なMPは、1つのGPUのメモリ容量を4倍にするのとほぼ同じであり、ハードウェアの残りを無視します。さらに、データのコピーのオーバーヘッドがあることを忘れてはいけません。したがって、4枚の6GBのカードは、データのコピーのオーバーヘッドがない1枚の24GBのカードと同じサイズを収容できるでしょうが、後者はトレーニングをより迅速に完了します。ただし、たとえば40GBのカードがあり、45GBのモデルを収める必要がある場合、勾配とオプティマイザの状態のためにほとんど収めることができません。
+- 共有の埋め込みは、GPU間でコピーする必要があるかもしれません。
+
+パイプライン並列処理(PP)は、ほぼ単純なMPと同じですが、GPUがアイドル状態になる問題を解決し、入力バッチをマイクロバッチに分割し、パイプラインを人工的に作成することにより、異なるGPUが計算プロセスに同時に参加できるようにします。
+
+以下は、[GPipe論文](https://ai.googleblog.com/2019/03/introducing-gpipe-open-source-library.html)からの図で、上部には単純なMP、下部にはPPが示されています:
+
+
+
+この図から、PPがGPUがアイドル状態の領域である「バブル」を少なく持つことがわかります。アイドル状態の部分は「バブル」と呼ばれます。
+
+図の両方の部分は、4つのGPUがパイプラインに参加している4の次元の並列性を示しています。つまり、4つのパイプステージF0、F1、F2、F3のフォワードパスがあり、逆順のバックワードパスB3、B2、B1、B0があります。
+
+PPは調整する新しいハイパーパラメータを導入します。それは `chunks` で、同じパイプステージを通じて連続して送信されるデータのチャンクの数を定義します。たとえば、下の図では `chunks=4` が表示されています。GPU0はチャンク0、1、2、3(F0,0、F0,1、F0,2、F0,3)で同じフォワードパスを実行し、他のGPUが作業を開始し始めるのを待ってから、GPU0はチャンク3、2、1、0(B0,3、B0,2、B0,1、B0,0)で逆順パスを実行します。
+
+注意すべきは、概念的にはこれが勾配蓄積ステップ(GAS)と同じコンセプトであることです。PyTorchは `chunks` を使用し、DeepSpeedは同じハイパーパラメータをGASと呼びます。
+
+`chunks` の導入により、PPはマイクロバッチ(MBS)の概念を導入します。DPはグローバルデータバッチサイズをミニバッチに分割します。したがって、DPの次数が4で、グローバルバッチサイズが1024の場合、4つのミニバッチ(それぞれ256)に分割されます(1024/4)。そして、`chunks`(またはGAS)の数が32である場合、マイクロバッチサイズは8になります(256/32)。各パイプラインステージは1つのマイクロバッチで作業します。
+
+DP + PPセットアップのグローバルバッチサイズを計算するには、`mbs*chunks*dp_degree`(`8*32*4=1024`)を行います。
+
+図に戻りましょう。
+
+`chunks=1` であれば、非効率な単純なMPになります。非常に大きな `chunks` 値を使用すると、非常に小さなマイクロバッチサイズになり、効率があまり高くないかもしれません。したがって、GPUの効率的な利用を最大化する値を見つけるために実験する必要があります。これは、バブルのサイズを最小限にすることに対応する、すべての参加GPUにわたる高い並行GPU利用を可能にするためです。
+
+2つのソリューショングループがあります。従来のパイプラインAPIソリューションと、ユーザーのモデルを大幅に変更する必要があるより現代的なソリューションです。
+
+従来のパイプラインAPIソリューション:
+- PyTorch
+- DeepSpeed
+- Megatron-LM
+
+現代的なソリューション:
+- Varuna
+- Sagemaker
+
+従来のパイプラインAPIソリューションの問題点:
+- モデルをかなり変更する必要があるため、Pipelineはモジュールの通常のフローを`nn.Sequential`シーケンスに再書き込む必要があり、モデルの設計を変更することが必要です。
+- 現在、Pipeline APIは非常に制限的です。最初のパイプラインステージに渡されるPython変数のセットがある場合、回避策を見つける必要があります。現在、パイプラインインターフェースでは、唯一のテンソルまたはテンソルのタプルを入力と出力として要求しています。これらのテンソルはバッチサイズを最初の次元として持っている必要があります。パイプラインはミニバッチをマイクロバッチに分割します。可能な改善点については、こちらの議論が行われています:https://github.com/pytorch/pytorch/pull/50693
+- パイプステージのレベルでの条件付き制御フローは不可能です。例えば、T5のようなエンコーダーデコーダーモデルは、条件付きエンコーダーステージを処理するために特別な回避策が必要です。
+- 各レイヤーを配置する必要があるため、1つのモデルの出力が他のモデルの入力になるようにします。
+
+VarunaとSageMakerとの実験はまだ行っていませんが、彼らの論文によれば、上記で述べた問題のリストを克服し、ユーザーのモデルにははるかに小さな変更しか必要としないと報告されています。
+
+実装:
+
+- [Pytorch](https://pytorch.org/docs/stable/pipeline.html) (initial support in pytorch-1.8, and progressively getting improved in 1.9 and more so in 1.10). Some [examples](https://github.com/pytorch/pytorch/blob/master/benchmarks/distributed/pipeline/pipe.py)
+- [DeepSpeed](https://www.deepspeed.ai/tutorials/pipeline/)
+- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM) has an internal implementation - no API.
+- [Varuna](https://github.com/microsoft/varuna)
+- [SageMaker](https://arxiv.org/abs/2111.05972) - this is a proprietary solution that can only be used on AWS.
+- [OSLO](https://github.com/tunib-ai/oslo) - この実装は、Hugging Face Transformersに基づいています。
+
+🤗 Transformersのステータス: この執筆時点では、いずれのモデルも完全なPP(パイプライン並列処理)をサポートしていません。GPT2モデルとT5モデルは単純なMP(モデル並列処理)サポートを持っています。主な障害は、モデルを`nn.Sequential`に変換できず、すべての入力がテンソルである必要があることです。現在のモデルには、変換を非常に複雑にする多くの機能が含まれており、これらを削除する必要があります。
+
+他のアプローチ:
+
+DeepSpeed、Varuna、およびSageMakerは、[交互にパイプラインを実行](https://docs.aws.amazon.com/sagemaker/latest/dg/model-parallel-core-features.html)するコンセプトを使用しています。ここでは、バックワードパスを優先させてバブル(アイドル時間)をさらに最小限に抑えます。
+
+Varunaは、最適なスケジュールを発見するためにシミュレーションを使用してスケジュールをさらに改善しようとします。
+
+OSLOは、`nn.Sequential`の変換なしでTransformersに基づくパイプライン並列処理を実装しています。
+
+## Tensor Parallelism
+
+テンソル並列処理では、各GPUがテンソルのスライスのみを処理し、全体が必要な操作のためにのみ完全なテンソルを集約します。
+
+このセクションでは、[Megatron-LM](https://github.com/NVIDIA/Megatron-LM)論文からのコンセプトと図を使用します:[GPUクラスタでの効率的な大規模言語モデルトレーニング](https://arxiv.org/abs/2104.04473)。
+
+どのトランスフォーマの主要な構築要素は、完全に接続された`nn.Linear`に続く非線形アクティベーション`GeLU`です。
+
+Megatronの論文の表記法に従って、行列の乗算部分を`Y = GeLU(XA)`と書くことができます。ここで、`X`と`Y`は入力ベクトルと出力ベクトルで、`A`は重み行列です。
+
+行列の計算を行列形式で見ると、行列乗算を複数のGPUで分割できる方法が簡単に理解できます:
+
+
+重み行列`A`を`N`個のGPUに対して列ごとに分割し、並列で行列乗算`XA_1`から`XA_n`を実行すると、`N`個の出力ベクトル`Y_1、Y_2、...、Y_n`が得られ、それらを独立して`GeLU`に供給できます:
+
+
+この原理を使用して、最後まで同期が必要ないまま、任意の深さのMLPを更新できます。Megatron-LMの著者はそのための有用なイラストを提供しています:
+
+
+マルチヘッドアテンションレイヤーを並列化することはさらに簡単です。それらは既に複数の独立したヘッドを持っているため、本質的に並列です!
+
+
+特別な考慮事項:TPには非常に高速なネットワークが必要であり、したがって1つのノードを超えてTPを実行しないことがお勧めされません。実際には、1つのノードに4つのGPUがある場合、最大のTP度数は4です。TP度数8が必要な場合は、少なくとも8つのGPUを持つノードを使用する必要があります。
+
+このセクションは、元のより詳細な[TPの概要](https://github.com/huggingface/transformers/issues/10321#issuecomment-783543530)に基づいています。
+by [@anton-l](https://github.com/anton-l)。
+
+SageMakerは、より効率的な処理のためにTPとDPを組み合わせて使用します。
+
+代替名:
+- [DeepSpeed](https://github.com/microsoft/DeepSpeed)はこれを「テンソルスライシング」と呼びます。詳細は[DeepSpeedの特徴](https://www.deepspeed.ai/training/#model-parallelism)をご覧ください。
+
+実装例:
+- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)には、モデル固有の内部実装があります。
+- [parallelformers](https://github.com/tunib-ai/parallelformers)(現時点では推論のみ)。
+- [SageMaker](https://arxiv.org/abs/2111.05972) - これはAWSでのみ使用できるプロプライエタリなソリューションです。
+- [OSLO](https://github.com/tunib-ai/oslo)には、Transformersに基づいたテンソル並列実装があります。
+
+🤗 Transformersの状況:
+- コア: まだコアには実装されていません。
+- ただし、推論が必要な場合、[parallelformers](https://github.com/tunib-ai/parallelformers)はほとんどのモデルに対してサポートを提供します。これがコアに実装されるまで、これを使用できます。そして、トレーニングモードもサポートされることを期待しています。
+- Deepspeed-Inferenceでは、BERT、GPT-2、およびGPT-NeoモデルをCUDAカーネルベースの高速推論モードでサポートしています。詳細は[こちら](https://www.deepspeed.ai/tutorials/inference-tutorial/)をご覧ください。
+
+## DP+PP
+
+DeepSpeedの[パイプラインチュートリアル](https://www.deepspeed.ai/tutorials/pipeline/)からの次の図は、DPをPPと組み合わせる方法を示しています。
+
+
+
+ここで重要なのは、DPランク0がGPU2を見えなくし、DPランク1がGPU3を見えなくすることです。DPにとって、存在するのはGPU 0 と 1 のみで、それらの2つのGPUのようにデータを供給します。GPU0はPPを使用してGPU2に一部の負荷を「秘密裏に」オフロードし、GPU1も同様にGPU3を支援に引き入れます。
+
+各次元には少なくとも2つのGPUが必要ですので、ここでは少なくとも4つのGPUが必要です。
+
+実装例:
+- [DeepSpeed](https://github.com/microsoft/DeepSpeed)
+- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)
+- [Varuna](https://github.com/microsoft/varuna)
+- [SageMaker](https://arxiv.org/abs/2111.05972)
+- [OSLO](https://github.com/tunib-ai/oslo)
+
+🤗 Transformersの状況: まだ実装されていません
+
+## DP+PP+TP
+
+さらに効率的なトレーニングを行うために、3Dパラレリズムを使用し、PPをTPとDPと組み合わせます。これは次の図で示されています。
+
+
+
+この図は[3Dパラレリズム:兆パラメータモデルへのスケーリング](https://www.microsoft.com/en-us/research/blog/deepspeed-extreme-scale-model-training-for-everyone/)というブログ投稿から取得されたもので、おすすめの読み物です。
+
+各次元には少なくとも2つのGPUが必要ですので、ここでは少なくとも8つのGPUが必要です。
+
+実装例:
+- [DeepSpeed](https://github.com/microsoft/DeepSpeed) - DeepSpeedには、さらに効率的なDPであるZeRO-DPと呼ばれるものも含まれています。
+- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)
+- [Varuna](https://github.com/microsoft/varuna)
+- [SageMaker](https://arxiv.org/abs/2111.05972)
+- [OSLO](https://github.com/tunib-ai/oslo)
+
+🤗 Transformersの状況: まだ実装されていません。PPとTPがないため。
+
+## ZeRO DP+PP+TP
+
+DeepSpeedの主要な機能の1つはZeROで、これはDPの拡張機能です。これについてはすでに「ZeROデータ並列化」で説明されています。通常、これは単独で動作する機能で、PPやTPは必要ありません。しかし、PPとTPと組み合わせることもできます。
+
+ZeRO-DPがPPと組み合わされる場合、通常はZeROステージ1(オプティマイザーシャーディング)のみが有効になります。
+
+ZeROステージ2(勾配シャーディング)をパイプライン並列化と組み合わせて使用する理論的な可能性はありますが、性能に悪影響を及ぼします。各マイクロバッチごとに勾配をシャーディングする前に、勾配を集約するための追加のリダクションスキャッター集計が必要で、通信オーバーヘッドが発生する可能性があります。パイプライン並列化の性質上、小さなマイクロバッチが使用され、計算の集中度(マイクロバッチサイズ)をバランスにかけ、パイプラインバブル(マイクロバッチ数)を最小限に抑えることに焦点が当てられています。したがって、これらの通信コストは影響を及ぼすでしょう。
+
+さらに、PPには通常よりも少ない層が含まれており、メモリの節約はそれほど大きくありません。PPは既に勾配サイズを「1/PP」に削減するため、勾配シャーディングの節約は純粋なDPよりもはるかに重要ではありません。
+
+ZeROステージ3も同様の理由で適していません - より多くのノード間通信が必要です。
+
+そして、ZeROを持っているので、もう一つの利点はZeRO-Offloadです。これはステージ1オプティマイザーステートをCPUにオフロードできます。
+
+実装例:
+- [Megatron-DeepSpeed](https://github.com/microsoft/Megatron-DeepSpeed)と[BigScienceからのMegatron-Deepspeed](https://github.com/bigscience-workshop/Megatron-DeepSpeed)は、前者のリポジトリのフォークです。
+- [OSLO](https://github.com/tunib-ai/oslo)
+
+重要な論文:
+
+- [DeepSpeedとMegatronを使用したMegatron-Turing NLG 530Bのトレーニング](https://arxiv.org/abs/2201.11990)
+
+🤗 Transformersの状況: まだ実装されていません。PPとTPがないため。
+
+
+## FlexFlow
+
+[FlexFlow](https://github.com/flexflow/FlexFlow)は、わずかに異なるアプローチで並列化の問題を解決します。
+
+論文: [Zhihao Jia、Matei Zaharia、Alex Aikenによる "Deep Neural Networksのデータとモデルの並列化を超えて"](https://arxiv.org/abs/1807.05358)
+
+FlexFlowは、サンプル-オペレータ-属性-パラメータの4D並列化を行います。
+
+1. サンプル = データ並列化(サンプル単位の並列化)
+2. オペレータ = 単一の操作をいくつかのサブ操作に並列化
+3. 属性 = データ並列化(長さ方向の並列化)
+4. パラメータ = モデル並列化(次元に関係なく、水平または垂直)
+
+例:
+* サンプル
+
+シーケンス長512の10バッチを考えてみましょう。これらをサンプル次元で2つのデバイスに並列化すると、10 x 512が5 x 2 x 512になります。
+
+* オペレータ
+
+層正規化を行う場合、まずstdを計算し、次にmeanを計算し、データを正規化できます。オペレータの並列化により、stdとmeanを並列に計算できます。したがって、オペレータ次元で2つのデバイス(cuda:0、cuda:1)に並列化すると、最初に入力データを両方のデバイスにコピーし、cuda:0でstdを計算し、cuda:1でmeanを同時に計算します。
+
+* 属性
+
+10バッチの512長があります。これらを属性次元で2つのデバイスに並列化すると、10 x 512が10 x 2 x 256になります。
+
+* パラメータ
+
+これはテンソルモデルの並列化または単純な層ごとのモデルの並列化と似ています。
+
+このフレームワークの重要性は、(1)GPU/TPU/CPU対(2)RAM/DRAM対(3)高速内部接続/低速外部接続などのリソースを取り、これらすべてをアルゴリズムによって自動的に最適化することです。どの並列化をどこで使用するかをアルゴリズム的に決定します。
+
+非常に重要な側面の1つは、FlexFlowは静的で固定のワークロードを持つモデルのために設計されており、動的な動作を持つモデルはイテレーションごとに異なる並列化戦略を好む場合があることです。
+
+したがって、このフレームワークの約束は非常に魅力的です。選択したクラスタで30分間のシミュレーションを実行し、この特定の環境を最適に利用するための最良の戦略を提供します。部分を追加/削除/置換すると、それに対して実行して再最適化プランを作成します。その後、トレーニングできます。異なるセットアップには独自の最適化があります。
+
+🤗 Transformersの現在の状況: まだ統合されていません。すでに[transformers.utils.fx](https://github.com/huggingface/transformers/blob/master/src/transformers/utils/fx.py)を使用してモデルがFXトレース可能であるため、FlexFlowを動作させるために必要な手順を誰かが見つける必要があります。
+
+## Which Strategy To Use When
+
+ここでは、どの並列化戦略をいつ使用するかの非常におおまかなアウトラインを示します。各リストの最初が通常よりも速いことが一般的です。
+
+**⇨ 単一GPU**
+
+* モデルが単一GPUに収まる場合:
+
+ 1. 通常の使用
+
+* モデルが単一GPUに収まらない場合:
+
+ 1. ZeRO + CPUをオフロードし、オプションでNVMeをオフロード
+ 2. 上記に加えて、最大のレイヤーが単一GPUに収まらない場合、[Memory Centric Tiling](https://deepspeed.readthedocs.io/en/latest/zero3.html#memory-centric-tiling)(詳細は以下参照)を有効化
+
+* 最大のレイヤーが単一GPUに収まらない場合:
+
+ 1. ZeROを使用しない場合 - TPを有効化する必要があります。なぜなら、PPだけでは収めることができないからです。
+ 2. ZeROを使用する場合は、上記の「単一GPU」のエントリと同じものを参照してください
+
+**⇨ 単一ノード/マルチGPU**
+
+* モデルが単一GPUに収まる場合:
+
+ 1. DDP - 分散データ並列
+ 2. ZeRO - 状況と使用される構成に依存して速いかどうかが異なることがあります
+
+* モデルが単一GPUに収まらない場合:
+
+ 1. PP
+ 2. ZeRO
+ 3. TP
+
+ 非常に高速なノード内接続がNVLINKまたはNVSwitchである場合、これらのすべてはほとんど同等の性能です。これらがない場合、PPはTPまたはZeROよりも速くなります。TPの度合いも違いを生じるかもしれません。特定のセットアップで勝者を見つけるために実験するのが最善です。
+
+ TPはほとんど常に単一ノード内で使用されます。つまり、TPサイズ <= ノードあたりのGPUです。
+
+* 最大のレイヤーが単一GPUに収まらない場合:
+
+ 1. ZeROを使用しない場合 - TPを使用する必要があります。なぜなら、PPだけでは収めることができないからです。
+ 2. ZeROを使用する場合は、上記の「単一GPU」のエントリと同じものを参照してください
+
+**⇨ マルチノード/マルチGPU**
+
+* 高速なノード間接続がある場合:
+
+ 1. ZeRO - モデルへのほとんどの変更が不要です
+ 2. PP+TP+DP - 通信が少なく、モデルに大規模な変更が必要です
+
+* 遅いノード間接続があり、GPUメモリが少ない場合:
+
+ 1. DP+PP+TP+ZeRO-1
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_gpu_one.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_gpu_one.md
new file mode 100644
index 0000000000000000000000000000000000000000..2c2bc540e48384fb8729d7ba5a0cc3ecf0b37a47
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_gpu_one.md
@@ -0,0 +1,438 @@
+
+
+# Methods and tools for efficient training on a single GPU
+
+このガイドでは、メモリの利用効率を最適化し、トレーニングを高速化することで、モデルのトレーニング効率を向上させるために使用できる実用的なテクニックを紹介します。トレーニング中にGPUがどのように利用されるかを理解したい場合は、最初に「[モデルトレーニングの解剖学](model_memory_anatomy)」のコンセプトガイドを参照してください。このガイドは実用的なテクニックに焦点を当てています。
+
+
+
+複数のGPUを搭載したマシンにアクセスできる場合、これらのアプローチは依然として有効です。さらに、[マルチGPUセクション](perf_train_gpu_many)で説明されている追加の方法を活用できます。
+
+
+
+大規模なモデルをトレーニングする際、同時に考慮すべき2つの側面があります:
+
+* データのスループット/トレーニング時間
+* モデルのパフォーマンス
+
+スループット(サンプル/秒)を最大化することは、トレーニングコストを低減させます。これは一般的に、GPUをできるだけ効果的に活用し、GPUメモリを限界まで埋めることによって達成されます。希望するバッチサイズがGPUメモリの制限を超える場合、勾配蓄積などのメモリ最適化テクニックが役立ちます。
+
+しかし、好みのバッチサイズがメモリに収まる場合、メモリを最適化するテクニックを適用する理由はありません。大きなバッチサイズを使用できるからといって、それを必ずしも使用すべきではありません。ハイパーパラメータの調整の一環として、どのバッチサイズが最良の結果を生み出すかを決定し、リソースを適切に最適化する必要があります。
+
+このガイドでカバーされている方法とツールは、トレーニングプロセスに与える影響に基づいて分類できます:
+
+
+| Method/tool | Improves training speed | Optimizes memory utilization |
+|:-----------------------------------------------------------|:------------------------|:-----------------------------|
+| [Batch size choice](#batch-size-choice) | Yes | Yes |
+| [Gradient accumulation](#gradient-accumulation) | No | Yes |
+| [Gradient checkpointing](#gradient-checkpointing) | No | Yes |
+| [Mixed precision training](#mixed-precision-training) | Yes | (No) |
+| [Optimizer choice](#optimizer-choice) | Yes | Yes |
+| [Data preloading](#data-preloading) | Yes | No |
+| [DeepSpeed Zero](#deepspeed-zero) | No | Yes |
+| [torch.compile](#using-torchcompile) | Yes | No |
+
+
+
+**注意**: 小さなモデルと大きなバッチサイズを使用する場合、メモリの節約が行われますが、大きなモデルと小さなバッチサイズを使用する場合、メモリの使用量が増加します。
+
+
+
+これらのテクニックは、[`Trainer`]でモデルをトレーニングしている場合や、純粋なPyTorchループを記述している場合の両方で利用できます。詳細な最適化の設定については、🤗 Accelerateを使用して[これらの最適化を設定できます](#using--accelerate)。
+
+これらの方法が十分な利益をもたらさない場合、以下のオプションを検討できます:
+* [効率的なソフトウェアプリビルドを備えたカスタムDockerコンテナの作成](#efficient-software-prebuilds)
+* [Mixture of Experts(MoE)を使用するモデルを検討](#mixture-of-experts)
+* [モデルをBetterTransformerに変換して、PyTorchネイティブのアテンションを活用](#using-pytorch-native-attention)
+
+最後に、これらの方法がまだ十分でない場合、A100などのサーバーグレードGPUに切り替えても、さらなる改善が必要かもしれません。これらのアプローチは、マルチGPUセットアップでも有効であり、[マルチGPUセクション](perf_train_gpu_many)で説明されている追加の並列化技術を活用できます。
+
+## Batch size choice
+
+最適なパフォーマンスを実現するために、適切なバッチサイズを特定することから始めましょう。2^Nのサイズのバッチサイズと入力/出力ニューロン数を使用することが推奨されています。通常、これは8の倍数ですが、使用するハードウェアとモデルのデータ型に依存することがあります。
+
+参考までに、NVIDIAの[入力/出力ニューロン数の推奨事項](https://docs.nvidia.com/deeplearning/performance/dl-performance-fully-connected/index.html#input-features)と[バッチサイズ](https://docs.nvidia.com/deeplearning/performance/dl-performance-fully-connected/index.html#batch-size)を確認してください(これらはGEMM(一般的な行列乗算)に関与します)。
+
+[Tensor Core要件](https://docs.nvidia.com/deeplearning/performance/dl-performance-matrix-multiplication/index.html#requirements-tc)では、データ型とハードウェアに基づいて乗数が定義されています。たとえば、fp16データ型の場合、64の倍数を使用することが推奨されます(A100 GPUの場合を除く)。
+
+小さなパラメータの場合、[次元量子化効果](https://docs.nvidia.com/deeplearning/performance/dl-performance-matrix-multiplication/index.html#dim-quantization)も考慮してください。これはタイリングが行われ、適切な乗数が大幅な高速化をもたらす場合があります。
+
+## Gradient Accumulation
+
+**勾配蓄積**メソッドは、GPUのメモリ容量の制約によって課せられる制限を超えた効果的なバッチサイズを実現するために、勾配を小さな増分で計算することを目的としています。このアプローチでは、モデルを順方向および逆方向に小さなバッチで反復的に計算し、その過程で勾配を蓄積します。十分な数の勾配が蓄積されたら、モデルの最適化ステップを実行します。勾配蓄積を使用することで、GPUのメモリ容量による制約を超えて**効果的なバッチサイズ**を増やすことができますが、勾配蓄積によって導入される追加の順方向および逆方向の計算はトレーニングプロセスを遅くする可能性があることに注意が必要です。
+
+`TrainingArguments`に`gradient_accumulation_steps`引数を追加することで、勾配蓄積を有効にすることができます:
+
+```py
+training_args = TrainingArguments(per_device_train_batch_size=1, gradient_accumulation_steps=4, **default_args)
+```
+
+上記の例では、効果的なバッチサイズは4になります。
+
+また、トレーニングループを完全に制御するために🤗 Accelerateを使用することもできます。🤗 Accelerateの例は、[このガイドの後半にある](#using--accelerate)で見つけることができます。
+
+できるだけGPUの使用率を最大限にすることが推奨されていますが、高い勾配蓄積ステップ数はトレーニングの遅延をより顕著にすることがあります。以下の例を考えてみましょう。`per_device_train_batch_size=4`の場合、勾配蓄積を使用しないとGPUの制限に達します。バッチサイズ64でトレーニングしたい場合、`per_device_train_batch_size`を1に設定し、`gradient_accumulation_steps`を64に設定しないでください。代わりに、`per_device_train_batch_size=4`を保持し、`gradient_accumulation_steps=16`を設定します。これにより、同じ効果的なバッチサイズが得られ、利用可能なGPUリソースが効果的に活用されます。
+
+詳細な情報については、[RTX-3090用のバッチサイズと勾配蓄積のベンチマーク](https://github.com/huggingface/transformers/issues/14608#issuecomment-1004392537)および[A100用のバッチサイズと勾配蓄積のベンチマーク](https://github.com/huggingface/transformers/issues/15026#issuecomment-1005033957)を参照してください。
+
+## Gradient Checkpointing
+
+一部の大きなモデルは、バッチサイズを1に設定し、勾配蓄積を使用している場合でもメモリの問題に直面することがあります。これは、メモリストレージが必要な他のコンポーネントも存在するためです。
+
+前向きパスからのすべてのアクティベーションを保存して、逆向きパスで勾配を計算すると、かなりのメモリオーバーヘッドが発生します。逆向きパスで必要なときにアクティベーションを破棄して再計算する代替アプローチは、計算オーバーヘッドが大幅に増加し、トレーニングプロセスが遅くなります。
+
+**勾配チェックポイント**は、これらの2つのアプローチの折衷案を提供し、計算グラフ全体で戦略的に選択されたアクティベーションのみを保存するため、勾配を再計算する必要があるアクティベーションの一部だけを節約します。勾配チェックポイントの詳細については、[この素晴らしい記事](https://medium.com/tensorflow/fitting-larger-networks-into-memory-583e3c758ff9)を参照してください。
+
+[`Trainer`]で勾配チェックポイントを有効にするには、[`TrainingArguments`]に対応するフラグを渡します:
+
+
+```py
+training_args = TrainingArguments(
+ per_device_train_batch_size=1, gradient_accumulation_steps=4, gradient_checkpointing=True, **default_args
+)
+```
+
+代替手段として、🤗 Accelerateを使用することもできます - 🤗 Accelerateの例は[このガイドのさらに後ろにあります](#using--accelerate)。
+
+
+
+勾配チェックポイントを使用することでメモリ効率が向上する場合がありますが、トレーニング速度は約20%遅くなることに注意してください。
+
+
+
+## Mixed precision training
+
+**混合精度トレーニング**は、モデルのトレーニングの計算効率を最適化する技術で、特定の変数に対して低精度の数値フォーマットを利用します。従来、ほとんどのモデルは変数を表現し処理するために32ビット浮動小数点精度(fp32またはfloat32)を使用しています。しかし、すべての変数が正確な結果を得るためにこの高精度のレベルを必要としない場合があります。一部の変数の精度を16ビット浮動小数点(fp16またはfloat16)などのより低い数値フォーマットに変更することで、計算を高速化できます。このアプローチでは、一部の計算は半精度で行われ、一部はまだ完全な精度で行われるため、このアプローチは混合精度トレーニングと呼ばれています。
+
+最も一般的に混合精度トレーニングは、fp16(float16)データ型を使用して実現されますが、一部のGPUアーキテクチャ(アンペアアーキテクチャなど)ではbf16およびtf32(CUDA内部データ型)データ型も提供されています。これらのデータ型の違いについて詳しく知りたい場合は、[NVIDIAのブログ](https://developer.nvidia.com/blog/accelerating-ai-training-with-tf32-tensor-cores/)を確認してください。
+
+### fp16
+
+混合精度トレーニングの主な利点は、半精度(fp16)でアクティベーションを保存することから得られます。
+勾配も半精度で計算されますが、最適化ステップでは再び完全精度に変換されるため、ここではメモリは保存されません。
+混合精度トレーニングは計算速度を向上させる一方、特に小さなバッチサイズの場合、より多くのGPUメモリを使用することがあります。
+これは、モデルがGPU上に16ビットおよび32ビット精度の両方で存在するためです(GPU上の元のモデルの1.5倍)。
+
+混合精度トレーニングを有効にするには、`fp16`フラグを`True`に設定します:
+
+```py
+training_args = TrainingArguments(per_device_train_batch_size=4, fp16=True, **default_args)
+```
+
+🤗 Accelerateを使用する場合、🤗 Accelerateの例は[このガイドのさらに後ろにあります](#using--accelerate)。
+
+### BF16
+
+Ampereまたはそれ以降のハードウェアにアクセスできる場合、混合精度トレーニングと評価にbf16を使用できます。bf16はfp16よりも精度が劣りますが、はるかに大きな動的範囲を持っています。fp16では、持つことができる最大の数は `65535` であり、それを超える数値はオーバーフローを引き起こします。一方、bf16の数値は `3.39e+38` のように大きく、これはfp32とほぼ同じです - どちらも数値範囲に8ビットを使用しているためです。
+
+BF16を有効にするには、🤗 Trainerで以下のように設定します:
+
+
+```python
+training_args = TrainingArguments(bf16=True, **default_args)
+```
+
+
+### TF32
+
+アンペアハードウェアは、tf32という特別なデータ型を使用します。これは、fp32と同じ数値範囲(8ビット)を持っていますが、23ビットの精度ではなく、10ビットの精度(fp16と同じ)を持ち、合計で19ビットしか使用しません。これは通常のfp32トレーニングおよび推論コードを使用し、tf32サポートを有効にすることで、最大3倍のスループットの向上が得られる点で「魔法のよう」です。行う必要があるのは、次のコードを追加するだけです:
+
+```python
+import torch
+torch.backends.cuda.matmul.allow_tf32 = True
+torch.backends.cudnn.allow_tf32 = True
+```
+
+
+使用されているGPUがアンペアシリーズであると仮定し、CUDAは可能な限りtf32を使用するように自動的に切り替えます。
+
+[NVIDIAの研究によれば](https://developer.nvidia.com/blog/accelerating-ai-training-with-tf32-tensor-cores/)、ほとんどの機械学習トレーニングワークロードはtf32トレーニングとfp32トレーニングで同じ難解度と収束を示します。すでにfp16またはbf16混合精度を使用している場合、スループットの向上に役立つこともあります。
+
+🤗 Trainerでこのモードを有効にすることができます:
+
+
+```python
+TrainingArguments(tf32=True, **default_args)
+```
+
+
+
+tf32は`tensor.to(dtype=torch.tf32)`を介して直接アクセスできません。これは内部のCUDAデータ型です。tf32データ型を使用するには、`torch>=1.7`が必要です。
+
+
+
+tf32と他の精度に関する詳細な情報については、以下のベンチマークを参照してください:
+[RTX-3090](https://github.com/huggingface/transformers/issues/14608#issuecomment-1004390803)および
+[A100](https://github.com/huggingface/transformers/issues/15026#issuecomment-1004543189)。
+
+## Flash Attention 2
+
+transformersでFlash Attention 2統合を使用することで、トレーニングのスループットを向上させることができます。Flash Attention 2モジュールを含むモデルの読み込み方法については、[single GPU section](./perf_infer_gpu_one#Flash-Attention-2)の適切なセクションを確認して詳細を学びましょう。
+
+## オプティマイザの選択
+
+Transformerモデルをトレーニングするために最も一般的に使用されるオプティマイザはAdamまたはAdamW(重み減衰を伴うAdam)です。Adamは前回の勾配の移動平均を保存することで収束を達成しますが、モデルパラメータの数のオーダーの追加メモリフットプリントを追加します。これを解消するために、代替オプティマイザを使用できます。たとえば、[NVIDIA/apex](https://github.com/NVIDIA/apex)がインストールされている場合、`adamw_apex_fused`はすべてのサポートされているAdamWオプティマイザの中で最も高速なトレーニング体験を提供します。
+
+[`Trainer`]は、直接使用できるさまざまなオプティマイザを統合しており、`adamw_hf`、`adamw_torch`、`adamw_torch_fused`、`adamw_apex_fused`、`adamw_anyprecision`、`adafactor`、または`adamw_bnb_8bit`が含まれています。サードパーティの実装を介してさらに多くのオプティマイザを追加できます。
+
+AdamWオプティマイザの代替手段について詳しく見てみましょう:
+1. [`Trainer`]で使用可能な`adafactor`
+2. Trainerで使用可能な`adamw_bnb_8bit`は、デモンストレーション用に以下でサードパーティの統合が提供されています。
+
+比較のため、3Bパラメータモデル(例:「google-t5/t5-3b」)の場合:
+* 標準のAdamWオプティマイザは、各パラメータに8バイトを使用するため、24GBのGPUメモリが必要です(8 * 3 => 24GB)。
+* Adafactorオプティマイザは12GB以上必要です。各パラメータにわずか4バイト以上を使用するため、4 * 3と少し余分になります。
+* 8ビットのBNB量子化オプティマイザは、すべてのオプティマイザの状態が量子化されている場合、わずか6GBしか使用しません。
+
+### Adafactor
+
+Adafactorは、重み行列の各要素のために前回の平均を保存しません。代わりに、(行ごとと列ごとの平均の合計など)集
+
+
+```py
+training_args = TrainingArguments(per_device_train_batch_size=4, optim="adafactor", **default_args)
+```
+
+
+他のアプローチ(勾配蓄積、勾配チェックポイント、混合精度トレーニング)と組み合わせることで、スループットを維持しながら最大3倍の向上が見られることがあります!ただし、前述のように、Adafactorの収束性はAdamよりも悪いことがあります。
+
+### 8ビット Adam
+
+Adafactorのようにオプティマイザの状態を集約する代わりに、8ビットのAdamは完全な状態を保持し、それを量子化します。量子化とは、状態を低い精度で保存し、最適化のためだけに非量子化することを意味します。これは混合精度トレーニングの背後にあるアイデアと似ています。
+
+`adamw_bnb_8bit`を使用するには、単に[`TrainingArguments`]で`optim="adamw_bnb_8bit"`を設定するだけです:
+
+
+```py
+training_args = TrainingArguments(per_device_train_batch_size=4, optim="adamw_bnb_8bit", **default_args)
+```
+
+ただし、デモンストレーション目的で8ビットオプティマイザをサードパーティの実装を使用することもできます。これを統合する方法を確認するためです。
+
+まず、8ビットAdamオプティマイザを実装した`bitsandbytes`ライブラリをインストールするために、GitHub [リポジトリ](https://github.com/TimDettmers/bitsandbytes)内のインストールガイドに従ってください。
+
+次に、オプティマイザを初期化する必要があります。これには2つのステップが含まれます:
+* まず、モデルのパラメータを2つのグループに分けます - 重み減衰を適用するべきグループと、適用すべきでないグループです。通常、バイアスとレイヤー正規化パラメータは重み減衰されません。
+* 次に、以前に使用したAdamWオプティマイザと同じパラメータを使用するために、いくつかの引数の調整を行います。
+
+
+```py
+import bitsandbytes as bnb
+from torch import nn
+from transformers.trainer_pt_utils import get_parameter_names
+
+training_args = TrainingArguments(per_device_train_batch_size=4, **default_args)
+
+decay_parameters = get_parameter_names(model, [nn.LayerNorm])
+decay_parameters = [name for name in decay_parameters if "bias" not in name]
+optimizer_grouped_parameters = [
+ {
+ "params": [p for n, p in model.named_parameters() if n in decay_parameters],
+ "weight_decay": training_args.weight_decay,
+ },
+ {
+ "params": [p for n, p in model.named_parameters() if n not in decay_parameters],
+ "weight_decay": 0.0,
+ },
+]
+
+optimizer_kwargs = {
+ "betas": (training_args.adam_beta1, training_args.adam_beta2),
+ "eps": training_args.adam_epsilon,
+}
+optimizer_kwargs["lr"] = training_args.learning_rate
+adam_bnb_optim = bnb.optim.Adam8bit(
+ optimizer_grouped_parameters,
+ betas=(training_args.adam_beta1, training_args.adam_beta2),
+ eps=training_args.adam_epsilon,
+ lr=training_args.learning_rate,
+)
+```
+
+最後に、カスタムオプティマイザを`Trainer`に引数として渡します:
+
+
+```py
+trainer = Trainer(model=model, args=training_args, train_dataset=ds, optimizers=(adam_bnb_optim, None))
+```
+
+他のアプローチ(勾配蓄積、勾配チェックポイント、混合精度トレーニング)と組み合わせることで、Adafactorの使用と同等以上の3倍のメモリ改善およびわずかに高いスループットを期待できます。
+
+### multi_tensor
+
+pytorch-nightlyは、多くの小さな特徴テンソルがある状況のオプティマイザを大幅に高速化するはずの`torch.optim._multi_tensor`を導入しました。これは最終的にはデフォルトになるはずですが、それを早く試してみたい場合は、このGitHub [issue](https://github.com/huggingface/transformers/issues/9965)をご覧ください。
+
+## データの事前読み込み
+
+優れたトレーニング速度に到達するための重要な要件の1つは、GPUが処理できる最大速度でデータを供給できる能力です。デフォルトではすべてがメインプロセスで行われ、データをディスクから十分速く読み取ることができない場合、GPUのアンダーユーティリゼーションを引き起こすボトルネックが発生する可能性があります。ボトルネックを減らすために、以下の引数を設定します:
+
+- `DataLoader(pin_memory=True, ...)` - データをCPUのピンメモリに事前読み込みし、通常、CPUからGPUメモリへの転送がはるかに高速化されます。
+- `DataLoader(num_workers=4, ...)` - データをより速く事前読み込みするために複数のワーカーを生成します。トレーニング中にGPUの利用状況の統計情報を確認し、100%から遠い場合、ワーカーの数を増やす実験を行ってください。もちろん、問題は他の場所にあるかもしれませんので、多くのワーカーが必ずしも性能向上につながるわけではありません。
+
+[`Trainer`]を使用する場合、対応する[`TrainingArguments`]は`dataloader_pin_memory`(デフォルトでは`True`)および`dataloader_num_workers`(デフォルトは`0`)です。
+
+## DeepSpeed ZeRO
+
+DeepSpeedは、🤗 Transformersと🤗 Accelerateと統合されたオープンソースのディープラーニング最適化ライブラリです。
+大規模なディープラーニングトレーニングの効率とスケーラビリティを向上させるために設計されたさまざまな機能と最適化を提供します。
+
+モデルが単一のGPUに収まり、小さなバッチサイズを収めるスペースがある場合、DeepSpeedを使用する必要はありません。それはむしろ遅くなります。ただし、モデルが単一のGPUに収まらない場合、または小さなバッチを収めることができない場合、DeepSpeed ZeRO + CPU OffloadまたはNVMe Offloadを利用できます。この場合、[ライブラリを別途インストール](main_classes/deepspeed#installation)し、設定ファイルを作成し、DeepSpeedを起動するためのガイドをフォローする必要があります:
+
+* [`Trainer`]とのDeepSpeed統合の詳細ガイドについては、[該当するドキュメンテーション](main_classes/deepspeed)を確認してください。特に、[単一GPU用のデプロイメント](main_classes/deepspeed#deployment-with-one-gpu)に関するセクションです。DeepSpeedをノートブックで使用するにはいくつかの調整が必要ですので、[該当するガイド](main_classes/deepspeed#deployment-in-notebooks)もご覧ください。
+* 🤗 Accelerateを使用する場合は、[🤗 Accelerate DeepSpeedガイド](https://huggingface.co/docs/accelerate/en/usage_guides/deepspeed)を参照してください。
+
+## torch.compileの使用
+
+PyTorch 2.0は新しいコンパイル関数を導入しました。これは既存のPyTorchコードを変更する必要はありませんが、1行のコードを追加することでコードを最適化できます:`model = torch.compile(model)`。
+
+[`Trainer`]を使用する場合、[`TrainingArguments`]内の`torch_compile`オプションを渡すだけです:
+
+
+```python
+training_args = TrainingArguments(torch_compile=True, **default_args)
+```
+
+`torch.compile`は、既存のPyTorchプログラムからグラフを自動的に作成するためにPythonのフレーム評価APIを使用します。グラフをキャプチャした後、異なるバックエンドを展開して最適化されたエンジンに変換できます。
+詳細およびベンチマークについては、[PyTorchドキュメント](https://pytorch.org/get-started/pytorch-2.0/)を参照してください。
+
+`torch.compile`には、オプションの依存関係を持つ成長中のバックエンドのリストがあり、`torchdynamo.list_backends()`を呼び出して確認できます。最も一般的に使用される一部のバックエンドは次のとおりです。
+
+**デバッグ用バックエンド**:
+* `dynamo.optimize("eager")` - 抽出されたGraphModuleを実行するためにPyTorchを使用します。これはTorchDynamoの問題をデバッグする際に非常に役立ちます。
+* `dynamo.optimize("aot_eager")` - コンパイラーを使用しないAotAutogradを使用してAotAutogradの抽出されたフォワードおよびバックワードグラフに対して単にPyTorch eagerを使用します。これはデバッグに役立ち、高速化は期待できません。
+
+**トレーニングおよび推論バックエンド**:
+* `dynamo.optimize("inductor")` - TorchInductorバックエンドを使用し、AotAutogradおよびcudagraphsを活用してコード生成されたTritonカーネルを使用します [詳細はこちら](https://dev-discuss.pytorch.org/t/torchinductor-a-pytorch-native-compiler-with-define-by-run-ir-and-symbolic-shapes/747)
+* `dynamo.optimize("nvfuser")` - nvFuser with TorchScriptを使用します。 [詳細はこちら](https://dev-discuss.pytorch.org/t/tracing-with-primitives-update-1-nvfuser-and-its-primitives/593)
+* `dynamo.optimize("aot_nvfuser")` - nvFuser with AotAutogradを使用します。 [詳細はこちら](https://dev-discuss.pytorch.org/t/tracing-with-primitives-update-1-nvfuser-and-its-primitives/593)
+* `dynamo.optimize("aot_cudagraphs")` - AotAutogradを使用してcudagraphsを使用します。 [詳細はこちら](https://github.com/pytorch/torchdynamo/pull/757)
+
+**推論専用バックエンド**:
+* `dynamo.optimize("ofi")` - Torchscriptの`optimize_for_inference`を使用します。 [詳細はこちら](https://pytorch.org/docs/stable/generated/torch.jit.optimize_for_inference.html)
+* `dynamo.optimize("fx2trt")` - Nvidia TensorRTを使用した推論の最適化にNvidia TensorRTを使用します。 [詳細はこちら](https://pytorch.org/TensorRT/tutorials/getting_started_with_fx_path.html)
+* `dynamo.optimize("onnxrt")` - CPU/GPUでの推論にONNX Runtimeを使用します。 [詳細はこちら](https://onnxruntime.ai/)
+* `dynamo.optimize("ipex")` - CPUでの推論にIPEXを使用します。 [詳細はこちら](https://github.com/intel/intel-extension-for-pytorch)
+
+🤗 Transformersを使用した`torch.compile`の使用例については、この[ブログ記事](https://www.philschmid.de/getting-started-pytorch-2-0-transformers)をご覧ください。
+
+## Using 🤗 Accelerate
+
+[🤗 Accelerate](https://huggingface.co/docs/accelerate/index)を使用すると、上記の方法を使用しながらトレーニングループを完全に制御でき、基本的には純粋なPyTorchでループを書くことができます。
+
+次に、[`TrainingArguments`]内で方法を組み合わせた場合を想
+
+```py
+training_args = TrainingArguments(
+ per_device_train_batch_size=1,
+ gradient_accumulation_steps=4,
+ gradient_checkpointing=True,
+ fp16=True,
+ **default_args,
+)
+```
+
+🤗 Accelerateを使用した完全なトレーニングループの例は、ほんの数行のコードです:
+
+```py
+from accelerate import Accelerator
+from torch.utils.data.dataloader import DataLoader
+
+dataloader = DataLoader(ds, batch_size=training_args.per_device_train_batch_size)
+
+if training_args.gradient_checkpointing:
+ model.gradient_checkpointing_enable()
+
+accelerator = Accelerator(fp16=training_args.fp16)
+model, optimizer, dataloader = accelerator.prepare(model, adam_bnb_optim, dataloader)
+
+model.train()
+for step, batch in enumerate(dataloader, start=1):
+ loss = model(**batch).loss
+ loss = loss / training_args.gradient_accumulation_steps
+ accelerator.backward(loss)
+ if step % training_args.gradient_accumulation_steps == 0:
+ optimizer.step()
+ optimizer.zero_grad()
+```
+
+まず、データセットを[`DataLoader`](https://pytorch.org/docs/stable/data.html#torch.utils.data.DataLoader)でラップします。
+次に、モデルの[`~PreTrainedModel.gradient_checkpointing_enable`]メソッドを呼び出すことで勾配チェックポイントを有効にできます。
+[`Accelerator`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator)を初期化する際に、混合精度トレーニングを使用するかどうかを[`prepare`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator.prepare)の呼び出しで指定し、複数のGPUを使用する場合、`prepare`の間にデータローダーもワーカー間で分散されます。同じ[8ビットオプティマイザ](#8-bit-adam)を前の例から使用します。
+
+最後に、主要なトレーニングループを追加できます。`backward`の呼び出しは🤗 Accelerateによって処理されることに注意してください。また、勾配の蓄積がどのように機能するかも確認できます。損失を正規化しているため、蓄積の最後に平均を得て、十分なステップがあると最適化が実行されます。
+
+これらの最適化技術を🤗 Accelerateを使用して実装するのは、わずかなコード行で行うことができ、トレーニングループの柔軟性が向上します。すべての機能の詳細については、[Accelerateのドキュメント](https://huggingface.co/docs/accelerate/index)を参照してください。
+
+## Efficient Software Prebuilds
+
+PyTorchの[pipとcondaビルド](https://pytorch.org/get-started/locally/#start-locally)は、PyTorchを実行するのに十分なcudaツールキットで事前にビルドされていますが、cuda拡張をビルドする必要がある場合には不十分です。
+
+時折、追加の努力が必要な場合があります。たとえば、事前にコンパイルされていない`apex`などのライブラリを使用している場合です。また、システム全体で適切なcudaツールキットをインストールする方法を見つけることが難しい場合もあります。
+これらのシナリオに対処するために、PyTorchとNVIDIAはcuda拡張がすでに事前にビルドされているNGC dockerコンテナの新しいバージョンをリリースしました。プログラムをインストールするだけで、そのまま実行できます。
+
+このアプローチは、PyTorchのソースを調整したり、新しいカスタマイズされたビルドを作成したりしたい場合にも役立ちます。
+欲しいdockerイメージバージョンを見つけるには、まず[PyTorchのリリースノート](https://docs.nvidia.com/deeplearning/frameworks/pytorch-release-notes/)から始め、最新の月次リリースのいずれかを選択します。希望のリリースのリリースノートに移動し、環境のコンポーネントが必要なものと一致していることを確認します(NVIDIA Driverの要件も含む!)、その文書の一番上に行き、対応するNGCページに移動します。なぜかわからない場合は、[すべてのPyTorch NGCイメージのインデックス](https://ngc.nvidia.com/catalog/containers/nvidia:pytorch)です。
+
+次に、dockerイメージをダウンロードして展開する手順に従います。
+
+## Mixture of Experts
+
+最近の論文によれば、Transformerモデルに専門家の混合(MoE)を統合することで、トレーニング速度が4〜5倍向上し、推論も高速化されることが報告されています。
+
+より多くのパラメータがより良いパフォーマンスにつながることがわかっているため、この技術はトレーニングコストを増やすことなくパラメータの数を桁違いに増やすことを可能にします。
+
+このアプローチでは、他のFFN層の代わりにMoE層が配置され、各専門家をトークンの位置に応じてバランスよくトレーニングするゲート関数で構成されます。
+
+
+
+(出典: [GLAM](https://ai.googleblog.com/2021/12/more-efficient-in-context-learning-with.html))
+
+このアプローチの主な欠点は、GPUメモリをほぼ桁違いに多く必要とすることです。メモリ要件がはるかに大きいことがそのまま反映されます。より高いメモリ要件を克服する方法については、さまざまな蒸留およびアプローチが提案されています。
+
+ただし、直接のトレードオフがあります。数人の専門家を使用してベースモデルを2〜3倍小さくすることで、5倍小さなモデルにし、トレーニング速度を適度に向上させ、メモリ要件を適度に増やすことができます。
+
+関連するほとんどの論文および実装はTensorflow/TPUを中心に構築されています。
+
+- [GShard: Conditional Computation and Automatic Shardingを活用した巨大モデルのスケーリング](https://arxiv.org/abs/2006.16668)
+- [Switch Transformers: シンプルで効率的なスパース性を備えたトリリオンパラメータモデルへのスケーリング](https://arxiv.org/abs/2101.03961)
+- [GLaM: Generalist Language Model (GLaM)](https://ai.googleblog.com/2021/12/more-efficient-in-context-learning-with.html)
+
+PytorchにはDeepSpeedが構築したものもあります: [DeepSpeed-MoE: Advancing Mixture-of-Experts Inference and Training to Power Next-Generation AI Scale](https://arxiv.org/abs/2201.05596)、[Mixture of Experts](https://www.deepspeed.ai/tutorials/mixture-of-experts/) - ブログ記事: [1](https://www.microsoft.com/en-us/research/blog/deepspeed-powers-8x-larger-moe-model-training-with-high-performance/)、[2](https://www.microsoft.com/en-us/research/publication/scalable-and-efficient-moe-training-for-multitask-multilingual-models/)、大規模なTransformerベースの自然言語生成モデルの具体的な展開については、[ブログ記事](https://www.deepspeed.ai/2021/12/09/deepspeed-moe-nlg.html)、[Megatron-Deepspeedブランチ](https://github.com/microsoft/Megatron-DeepSpeed/tree/moe-training)を参照してください。
+
+
+## PyTorchネイティブアテンションとFlash Attentionの使用
+
+PyTorch 2.0では、ネイティブの[`torch.nn.functional.scaled_dot_product_attention`](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention.html)(SDPA)がリリースされ、[メモリ効率の高いアテンション](https://arxiv.org/abs/2112.05682)や[フラッシュアテンション](https://arxiv.org/abs/2205.14135)などの融合されたGPUカーネルの使用を可能にします。
+
+[`optimum`](https://github.com/huggingface/optimum)パッケージをインストールした後、関連する内部モジュールを置き換えて、PyTorchのネイティブアテンションを使用できます。以下のように設定します:
+
+
+```python
+model = model.to_bettertransformer()
+```
+
+変換後、通常通りモデルをトレーニングしてください。
+
+
+
+PyTorchネイティブの`scaled_dot_product_attention`演算子は、`attention_mask`が提供されていない場合にのみFlash Attentionにディスパッチできます。
+
+デフォルトでは、トレーニングモードでBetterTransformer統合はマスクサポートを削除し、バッチトレーニングにパディングマスクが必要ないトレーニングにしか使用できません。これは、例えばマスク言語モデリングや因果言語モデリングのような、バッチトレーニングにパディングマスクが不要なトレーニングの場合に該当します。BetterTransformerはパディングマスクが必要なタスクに対するモデルの微調整には適していません。
+
+
+
+SDPAを使用したアクセラレーションとメモリの節約について詳しく知りたい場合は、この[ブログ記事](https://pytorch.org/blog/out-of-the-box-acceleration/)をチェックしてください。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_special.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_special.md
new file mode 100644
index 0000000000000000000000000000000000000000..080ff66f4cf5628dd134c0ec5a0e10015604ad58
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_special.md
@@ -0,0 +1,24 @@
+
+
+# Training on Specialized Hardware
+
+
+
+注意: [単一GPUセクション](perf_train_gpu_one)で紹介されたほとんどの戦略(混合精度トレーニングや勾配蓄積など)および[マルチGPUセクション](perf_train_gpu_many)は一般的なトレーニングモデルに適用される汎用的なものですので、このセクションに入る前にそれを確認してください。
+
+
+
+このドキュメントは、専用ハードウェアでトレーニングする方法に関する情報を近日中に追加予定です。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_tpu.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_tpu.md
new file mode 100644
index 0000000000000000000000000000000000000000..aadd588ae84d35afb79f2ca89d9c0983c0634c37
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_tpu.md
@@ -0,0 +1,24 @@
+
+
+# Training on TPUs
+
+
+
+ 注意: [シングルGPUセクション](perf_train_gpu_one)で紹介されているほとんどの戦略(混合精度トレーニングや勾配蓄積など)および[マルチGPUセクション](perf_train_gpu_many)は一般的なモデルのトレーニングに適用できますので、このセクションに入る前にそれを確認してください。
+
+
+
+このドキュメントは、TPUでのトレーニング方法に関する情報をまもなく追加いたします。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_tpu_tf.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_tpu_tf.md
new file mode 100644
index 0000000000000000000000000000000000000000..3ffe88267cddeb9cb254be39d215c5f8a3ea64e2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perf_train_tpu_tf.md
@@ -0,0 +1,168 @@
+
+
+# Training on TPU with TensorFlow
+
+
+
+詳細な説明が不要で、単にTPUのコードサンプルを入手してトレーニングを開始したい場合は、[私たちのTPUの例のノートブックをチェックしてください!](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb)
+
+
+
+### What is a TPU?
+
+TPUは**Tensor Processing Unit(テンソル処理ユニット)**の略です。これらはGoogleが設計したハードウェアで、ニューラルネットワーク内のテンソル計算を大幅に高速化するために使用されます。これはGPUのようなものです。ネットワークのトレーニングと推論の両方に使用できます。一般的にはGoogleのクラウドサービスを介してアクセスされますが、Google ColabとKaggle Kernelsを通じても無料で小規模のTPUに直接アクセスできます。
+
+[🤗 TransformersのすべてのTensorFlowモデルはKerasモデルです](https://huggingface.co/blog/tensorflow-philosophy)ので、この文書のほとんどの方法は一般的にKerasモデル用のTPUトレーニングに適用できます!ただし、TransformersとDatasetsのHuggingFaceエコシステム(hug-o-system?)に固有のポイントもいくつかあり、それについては適用するときにそれを示します。
+
+### What kinds of TPU are available?
+
+新しいユーザーは、さまざまなTPUとそのアクセス方法に関する幅広い情報によく混乱します。理解するための最初の重要な違いは、**TPUノード**と**TPU VM**の違いです。
+
+**TPUノード**を使用すると、事実上リモートのTPUに間接的にアクセスします。別個のVMが必要で、ネットワークとデータパイプラインを初期化し、それらをリモートノードに転送します。Google ColabでTPUを使用すると、**TPUノード**スタイルでアクセスしています。
+
+TPUノードを使用すると、それに慣れていない人々にはかなり予期しない動作が発生することがあります!特に、TPUはPythonコードを実行しているマシンと物理的に異なるシステムに配置されているため、データはローカルマシンにローカルで格納されているデータパイプラインが完全に失敗します。代わりに、データはGoogle Cloud Storageに格納する必要があります。ここでデータパイプラインはリモートのTPUノードで実行されている場合でも、データにアクセスできます。
+
+
+
+すべてのデータを`np.ndarray`または`tf.Tensor`としてメモリに収めることができる場合、ColabまたはTPUノードを使用している場合でも、データをGoogle Cloud Storageにアップロードせずに`fit()`でトレーニングできます。
+
+
+
+
+
+**🤗 Hugging Face固有のヒント🤗:** TFコードの例でよく見るであろう`Dataset.to_tf_dataset()`とその高レベルのラッパーである`model.prepare_tf_dataset()`は、TPUノードで失敗します。これは、`tf.data.Dataset`を作成しているにもかかわらず、それが「純粋な」`tf.data`パイプラインではなく、`tf.numpy_function`または`Dataset.from_generator()`を使用して基盤となるHuggingFace `Dataset`からデータをストリームで読み込むことからです。このHuggingFace `Dataset`はローカルディスク上のデータをバックアップしており、リモートTPUノードが読み取ることができないためです。
+
+
+
+TPUにアクセスする第二の方法は、**TPU VM**を介してです。TPU VMを使用する場合、TPUが接続されているマシンに直接接続します。これはGPU VMでトレーニングを行うのと同様です。TPU VMは一般的にデータパイプラインに関しては特に作業がしやすく、上記のすべての警告はTPU VMには適用されません!
+
+これは主観的な文書ですので、こちらの意見です:**可能な限りTPUノードの使用を避けてください。** TPU VMよりも混乱しやすく、デバッグが難しいです。将来的にはサポートされなくなる可能性もあります - Googleの最新のTPUであるTPUv4は、TPU VMとしてのみアクセスできるため、TPUノードは将来的には「レガシー」のアクセス方法になる可能性が高いです。ただし、無料でTPUにアクセスできるのはColabとKaggle Kernelsの場合があります。その場合、どうしても使用しなければならない場合の取り扱い方法を説明しようとします!詳細は[TPUの例のノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb)で詳細な説明を確認してください。
+
+### What sizes of TPU are available?
+
+単一のTPU(v2-8/v3-8/v4-8)は8つのレプリカを実行します。TPUは数百から数千のレプリカを同時に実行できる**ポッド**に存在します。単一のTPUよりも多くのTPUを使用するが、ポッド全体ではない場合(たとえばv3-32)、TPUフリートは**ポッドスライス**として参照されます。
+
+Colabを介して無料のTPUにアクセスする場合、通常は単一のv2-8 TPUが提供されます。
+
+
+### I keep hearing about this XLA thing. What’s XLA, and how does it relate to TPUs?
+
+XLAは、TensorFlowとJAXの両方で使用される最適化コンパイラです。JAXでは唯一のコンパイラであり、TensorFlowではオプションですが(しかしTPUでは必須です!)、Kerasモデルをトレーニングする際に`model.compile()`に引数`jit_compile=True`を渡すことで最も簡単に有効にできます。エラーが発生せず、パフォーマンスが良好であれば、それはTPUに移行する準備が整った良い兆候です!
+
+TPU上でのデバッグは一般的にCPU/GPUよりも少し難しいため、TPUで試す前にまずCPU/GPUでXLAを使用してコードを実行することをお勧めします。もちろん、長時間トレーニングする必要はありません。モデルとデータパイプラインが期待通りに動作するかを確認するための数ステップだけです。
+
+
+
+XLAコンパイルされたコードは通常高速です。したがって、TPUで実行する予定がない場合でも、`jit_compile=True`を追加することでパフォーマンスを向上させることができます。ただし、以下のXLA互換性に関する注意事項に注意してください!
+
+
+
+
+
+**苦い経験から生まれたヒント:** `jit_compile=True`を使用することは、CPU/GPUコードがXLA互換であることを確認し、速度を向上させる良い方法ですが、実際にTPUでコードを実行する際には多くの問題を引き起こす可能性があります。 XLAコンパイルはTPU上で暗黙的に行われるため、実際にコードをTPUで実行する前にその行を削除することを忘れないでください!
+
+
+
+### How do I make my model XLA compatible?
+
+多くの場合、コードはすでにXLA互換かもしれません!ただし、XLAでは動作する通常のTensorFlowでも動作しないいくつかの要素があります。以下に、3つの主要なルールにまとめています:
+
+
+
+**🤗 HuggingFace固有のヒント🤗:** TensorFlowモデルと損失関数をXLA互換に書き直すために多くの努力を払っています。通常、モデルと損失関数はデフォルトでルール#1と#2に従っているため、`transformers`モデルを使用している場合はこれらをスキップできます。ただし、独自のモデルと損失関数を記述する場合は、これらのルールを忘れないでください!
+
+
+
+#### XLA Rule #1: Your code cannot have “data-dependent conditionals”
+
+これは、任意の`if`ステートメントが`tf.Tensor`内の値に依存していない必要があることを意味します。例えば、次のコードブロックはXLAでコンパイルできません!
+
+```python
+if tf.reduce_sum(tensor) > 10:
+ tensor = tensor / 2.0
+```
+
+これは最初は非常に制限的に思えるかもしれませんが、ほとんどのニューラルネットコードはこれを行う必要はありません。通常、この制約を回避するために`tf.cond`を使用するか(ドキュメントはこちらを参照)、条件を削除して代わりに指示変数を使用したりすることができます。次のように:
+
+```python
+sum_over_10 = tf.cast(tf.reduce_sum(tensor) > 10, tf.float32)
+tensor = tensor / (1.0 + sum_over_10)
+```
+
+このコードは、上記のコードとまったく同じ効果を持っていますが、条件を回避することで、XLAで問題なくコンパイルできることを確認します!
+
+#### XLA Rule #2: Your code cannot have “data-dependent shapes”
+
+これは、コード内のすべての `tf.Tensor` オブジェクトの形状が、その値に依存しないことを意味します。たとえば、`tf.unique` 関数はXLAでコンパイルできないので、このルールに違反します。なぜなら、これは入力 `Tensor` の一意の値の各インスタンスを含む `tensor` を返すためです。この出力の形状は、入力 `Tensor` の重複具合によって異なるため、XLAはそれを処理しないことになります!
+
+一般的に、ほとんどのニューラルネットワークコードはデフォルトでルール#2に従います。ただし、いくつかの一般的なケースでは問題が発生することがあります。非常に一般的なケースの1つは、**ラベルマスキング**を使用する場合です。ラベルを無視して損失を計算する場所を示すために、ラベルを負の値に設定する方法です。NumPyまたはPyTorchのラベルマスキングをサポートする損失関数を見ると、次のような[ブールインデックス](https://numpy.org/doc/stable/user/basics.indexing.html#boolean-array-indexing)を使用したコードがよく見られます:
+
+
+```python
+label_mask = labels >= 0
+masked_outputs = outputs[label_mask]
+masked_labels = labels[label_mask]
+loss = compute_loss(masked_outputs, masked_labels)
+mean_loss = torch.mean(loss)
+```
+
+このコードはNumPyやPyTorchでは完全に機能しますが、XLAでは動作しません!なぜなら、`masked_outputs`と`masked_labels`の形状はマスクされた位置の数に依存するため、これは**データ依存の形状**になります。ただし、ルール#1と同様に、このコードを書き直して、データ依存の形状なしでまったく同じ出力を生成できることがあります。
+
+
+```python
+label_mask = tf.cast(labels >= 0, tf.float32)
+loss = compute_loss(outputs, labels)
+loss = loss * label_mask # Set negative label positions to 0
+mean_loss = tf.reduce_sum(loss) / tf.reduce_sum(label_mask)
+```
+
+
+ここでは、データ依存の形状を避けるために、各位置で損失を計算してから、平均を計算する際に分子と分母の両方でマスクされた位置をゼロ化する方法を紹介します。これにより、最初のアプローチとまったく同じ結果が得られますが、XLA互換性を維持します。注意点として、ルール#1と同じトリックを使用します - `tf.bool`を`tf.float32`に変換して指標変数として使用します。これは非常に便利なトリックですので、自分のコードをXLAに変換する必要がある場合には覚えておいてください!
+
+#### XLA Rule #3: XLA will need to recompile your model for every different input shape it sees
+
+これは重要なルールです。これはつまり、入力形状が非常に変動的な場合、XLA はモデルを何度も再コンパイルする必要があるため、大きなパフォーマンスの問題が発生する可能性があるということです。これは NLP モデルで一般的に発生し、トークナイズ後の入力テキストの長さが異なる場合があります。他のモダリティでは、静的な形状が一般的であり、このルールはほとんど問題になりません。
+
+ルール#3を回避する方法は何でしょうか?鍵は「パディング」です - すべての入力を同じ長さにパディングし、次に「attention_mask」を使用することで、可変形状と同じ結果を得ることができますが、XLA の問題は発生しません。ただし、過度のパディングも深刻な遅延を引き起こす可能性があります - データセット全体で最大の長さにすべてのサンプルをパディングすると、多くの計算とメモリを無駄にする可能性があります!
+
+この問題には完璧な解決策はありませんが、いくつかのトリックを試すことができます。非常に便利なトリックの1つは、**バッチのサンプルを32または64トークンの倍数までパディングする**ことです。これにより、トークン数がわずかに増加するだけで、すべての入力形状が32または64の倍数である必要があるため、一意の入力形状の数が大幅に減少します。一意の入力形状が少ないと、XLA の再コンパイルが少なくなります!
+
+
+
+**🤗 HuggingFace に関する具体的なヒント🤗:** 弊社のトークナイザーとデータコレクターには、ここで役立つメソッドがあります。トークナイザーを呼び出す際に `padding="max_length"` または `padding="longest"` を使用して、パディングされたデータを出力するように設定できます。トークナイザーとデータコレクターには、一意の入力形状の数を減らすのに役立つ `pad_to_multiple_of` 引数もあります!
+
+
+
+### How do I actually train my model on TPU?
+
+一度トレーニングが XLA 互換性があることを確認し、(TPU Node/Colab を使用する場合は)データセットが適切に準備されている場合、TPU 上で実行することは驚くほど簡単です!コードを変更する必要があるのは、いくつかの行を追加して TPU を初期化し、モデルとデータセットが `TPUStrategy` スコープ内で作成されるようにすることだけです。これを実際に見るには、[TPU のサンプルノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb)をご覧ください!
+
+### Summary
+
+ここでは多くの情報が提供されましたので、TPU でモデルをトレーニングする際に以下のチェックリストを使用できます:
+
+- コードが XLA の三つのルールに従っていることを確認します。
+- CPU/GPU で `jit_compile=True` を使用してモデルをコンパイルし、XLA でトレーニングできることを確認します。
+- データセットをメモリに読み込むか、TPU 互換のデータセット読み込みアプローチを使用します([ノートブックを参照](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb))。
+- コードを Colab(アクセラレータを「TPU」に設定)または Google Cloud の TPU VM に移行します。
+- TPU 初期化コードを追加します([ノートブックを参照](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb))。
+- `TPUStrategy` を作成し、データセットの読み込みとモデルの作成が `strategy.scope()` 内で行われることを確認します([ノートブックを参照](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb))。
+- TPU に移行する際に `jit_compile=True` を外すのを忘れないでください!
+- 🙏🙏🙏🥺🥺🥺
+- `model.fit()` を呼び出します。
+- おめでとうございます!
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/performance.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/performance.md
new file mode 100644
index 0000000000000000000000000000000000000000..bcd3987c5535363dd6a8a92c77b1504578038437
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/performance.md
@@ -0,0 +1,68 @@
+
+
+# Performance and Scalability
+
+大規模なトランスフォーマーモデルのトレーニングおよび本番環境への展開はさまざまな課題を提起します。
+トレーニング中には、モデルが利用可能なGPUメモリよりも多くを必要としたり、トレーニング速度が遅かったりする可能性があります。
+デプロイフェーズでは、モデルが本番環境で必要なスループットを処理するのに苦労することがあります。
+
+このドキュメンテーションは、これらの課題を克服し、ユースケースに最適な設定を見つけるのに役立つことを目的としています。
+ガイドはトレーニングと推論のセクションに分かれており、それぞれ異なる課題と解決策が存在します。
+各セクション内には、トレーニング用のシングルGPU対マルチGPU、推論用のCPU対GPUなど、異なるハードウェア構成用の別々のガイドが用意されています。
+
+このドキュメントを出発点として、シナリオに合った方法に進むための情報源としてご利用ください。
+
+## Training
+
+大規模なトランスフォーマーモデルを効率的にトレーニングするには、GPUやTPUなどのアクセラレータが必要です。
+最も一般的なケースは、シングルGPUがある場合です。シングルGPUでのトレーニング効率を最適化するための一般的なアプローチを学ぶには、以下を参照してください。
+
+* [シングルGPUでの効率的なトレーニングのための方法とツール](perf_train_gpu_one): GPUメモリの効果的な利用、トレーニングの高速化などを支援する共通のアプローチを学ぶためにここから始めてください。
+* [マルチGPUトレーニングセクション](perf_train_gpu_many): マルチGPU環境に適用されるデータ、テンソル、パイプライン並列性など、さらなる最適化方法について詳細に学びます。
+* [CPUトレーニングセクション](perf_train_cpu): CPU上での混合精度トレーニングについて学びます。
+* [複数CPUでの効率的なトレーニング](perf_train_cpu_many): 分散CPUトレーニングについて学びます。
+* [TensorFlowでTPUを使用したトレーニング](perf_train_tpu_tf): TPUに慣れていない場合は、TPUでのトレーニングとXLAの使用についてのセクションを参照してください。
+* [トレーニングのためのカスタムハードウェア](perf_hardware): 独自のディープラーニング環境を構築する際のヒントやトリックを見つけます。
+* [Trainer APIを使用したハイパーパラメーター検索](hpo_train)
+
+## Inference
+
+本番環境で大規模なモデルを効率的に推論することは、それらをトレーニングすることと同じくらい難しいことがあります。
+以下のセクションでは、CPUおよびシングル/マルチGPU環境で推論を実行する手順について説明します。
+
+* [シングルCPUでの推論](perf_infer_cpu)
+* [シングルGPUでの推論](perf_infer_gpu_one)
+* [マルチGPU推論](perf_infer_gpu_many)
+* [TensorFlowモデルのXLA統合](tf_xla)
+
+## Training and inference
+
+モデルをトレーニングするか、それを使用して推論を実行するかに関係なく適用されるテクニック、ヒント、トリックがここにあります。
+
+* [大規模モデルのインスタンス化](big_models)
+* [パフォーマンスの問題のトラブルシューティング](debugging)
+
+## Contribute
+
+このドキュメントはまだ完全ではなく、さらに追加する必要がある項目がたくさんあります。
+追加や訂正が必要な場合は、遠慮せずにPRをオープンするか、詳細を議論するためにIssueを開始してください。
+
+AがBよりも優れているという貢献を行う際には、再現可能なベンチマークやその情報の出典へのリンクを含めてみてください(あなた自身の情報である場合を除く)。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perplexity.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perplexity.md
new file mode 100644
index 0000000000000000000000000000000000000000..368a301ec3ab4a36c6a21086e4ba748aad242a5e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/perplexity.md
@@ -0,0 +1,116 @@
+
+
+# Perplexity of fixed-length models
+
+[[open-in-colab]]
+
+パープレキシティ(PPL)は言語モデルの評価に最も一般的な指標の1つです。深入りする前に、この指標は特に古典的な言語モデル(時にはオートレグレッシブまたは因果言語モデルとも呼ばれる)に適用され、BERTなどのマスクされた言語モデルには適していないことに注意すべきです(モデルの概要を参照してください[モデルの概要](model_summary))。
+
+パープレキシティは、シーケンスの指数平均負の対数尤度として定義されます。トークン化されたシーケンス \\(X = (x_0, x_1, \dots, x_t)\\) がある場合、\\(X\\) のパープレキシティは次のように表されます。
+
+$$\text{PPL}(X) = \exp \left\{ {-\frac{1}{t}\sum_i^t \log p_\theta (x_i|x_{
+
+サポートされているタスクと利用可能なパラメータの完全な一覧については、[`pipeline`]のドキュメンテーションをご覧ください。
+
+
+
+## Pipeline usage
+
+各タスクには関連する[`pipeline`]がありますが、タスク固有の[`pipeline`]を使用する代わりに、すべてのタスク固有のパイプラインを含む一般的な[`pipeline`]の抽象化を使用すると、より簡単です。[`pipeline`]は自動的にデフォルトのモデルと、タスクの推論が可能な前処理クラスを読み込みます。
+
+1. [`pipeline`]を作成し、推論タスクを指定して始めます:
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline(task="automatic-speech-recognition")
+```
+
+2. [`pipeline`]に入力テキストを渡します:
+
+```python
+>>> generator("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': 'I HAVE A DREAM BUT ONE DAY THIS NATION WILL RISE UP LIVE UP THE TRUE MEANING OF ITS TREES'}
+```
+
+チェックアウトできなかったか? [Hubの最もダウンロードされた自動音声認識モデル](https://huggingface.co/models?pipeline_tag=automatic-speech-recognition&sort=downloads) のいくつかを見て、より良い転写を得ることができるかどうかを確認してみてください。
+[openai/whisper-large](https://huggingface.co/openai/whisper-large) を試してみましょう:
+
+```python
+>>> generator = pipeline(model="openai/whisper-large")
+>>> generator("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+この結果はより正確に見えますね!
+異なる言語、専門分野に特化したモデル、その他のモデルについては、Hubをチェックすることを強くお勧めします。
+Hubでは、ブラウザから直接モデルの結果をチェックして、他のモデルよりも適しているか、特殊なケースをよりよく処理できるかを確認できます。
+そして、あなたのユースケースに適したモデルが見つからない場合、いつでも[トレーニング](training)を開始できます!
+
+複数の入力がある場合、入力をリストとして渡すことができます:
+
+```py
+generator(
+ [
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac",
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/1.flac",
+ ]
+)
+```
+
+データセット全体を繰り返し処理したり、ウェブサーバーで推論に使用したい場合は、専用の部分をチェックしてください。
+
+[データセットでパイプラインを使用する](#using-pipeline-in-a-dataset)
+
+[ウェブサーバーでパイプラインを使用する](./pipeline_webserver)
+
+
+
+## パラメータ
+
+[`pipeline`]は多くのパラメータをサポートしており、一部はタスク固有であり、一部はすべてのパイプラインに共通です。
+一般的には、どこでもパラメータを指定できます:
+
+```py
+generator = pipeline(model="openai/whisper-large", my_parameter=1)
+out = generator(...) # これは `my_parameter=1` を使用します。
+out = generator(..., my_parameter=2) # これは上書きして `my_parameter=2` を使用します。
+out = generator(...) # これは再び `my_parameter=1` を使用します。
+```
+
+3つの重要なものを確認しましょう:
+
+### Device
+
+`device=n` を使用すると、パイプラインはモデルを指定したデバイスに自動的に配置します。
+これは、PyTorchまたはTensorflowを使用しているかどうかに関係なく機能します。
+
+```py
+generator = pipeline(model="openai/whisper-large", device=0)
+```
+
+もしモデルが単一のGPUには大きすぎる場合、`device_map="auto"`を設定して、🤗 [Accelerate](https://huggingface.co/docs/accelerate) にモデルの重みをどのようにロードし、保存するかを自動的に決定させることができます。
+
+```python
+#!pip install accelerate
+generator = pipeline(model="openai/whisper-large", device_map="auto")
+```
+
+注意: `device_map="auto"` が渡された場合、`pipeline` をインスタンス化する際に `device=device` 引数を追加する必要はありません。そうしないと、予期しない動作に遭遇する可能性があります!
+
+### Batch size
+
+デフォルトでは、パイプラインは詳細について[こちら](https://huggingface.co/docs/transformers/main_classes/pipelines#pipeline-batching)で説明されている理由から、推論をバッチ処理しません。その理由は、バッチ処理が必ずしも速くないためであり、実際にはいくつかのケースでかなり遅くなることがあるからです。
+
+ただし、あなたのユースケースで機能する場合は、次のように使用できます:
+
+```py
+generator = pipeline(model="openai/whisper-large", device=0, batch_size=2)
+audio_filenames = [f"audio_{i}.flac" for i in range(10)]
+texts = generator(audio_filenames)
+```
+
+これにより、パイプラインは提供された10個のオーディオファイルでパイプラインを実行しますが、
+モデルにはバッチ処理がより効果的であるGPU上にあり、バッチ処理を行うための追加のコードは必要ありません。
+出力は常にバッチ処理なしで受け取ったものと一致するはずです。これは単にパイプラインからより高速な処理を得るための方法として提供されています。
+
+パイプラインは、バッチ処理のいくつかの複雑さを軽減することもできます。なぜなら、一部のパイプラインでは、
+モデルで処理するために1つのアイテム(長いオーディオファイルのようなもの)を複数の部分に分割する必要がある場合があるからです。
+パイプラインはこれをあなたのために実行します。[*チャンクバッチ処理*](./main_classes/pipelines#pipeline-chunk-batching)として知られるものを実行します。
+
+### Task specific parameters
+
+すべてのタスクは、タスク固有のパラメータを提供し、追加の柔軟性とオプションを提供して、作業をスムーズに進めるのに役立ちます。
+たとえば、[`transformers.AutomaticSpeechRecognitionPipeline.__call__`]メソッドには、ビデオの字幕作成に有用な`return_timestamps`パラメータがあります。
+
+```py
+>>> # Not using whisper, as it cannot provide timestamps.
+>>> generator = pipeline(model="facebook/wav2vec2-large-960h-lv60-self", return_timestamps="word")
+>>> generator("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': 'I HAVE A DREAM BUT ONE DAY THIS NATION WILL RISE UP AND LIVE OUT THE TRUE MEANING OF ITS CREED', 'chunks': [{'text': 'I', 'timestamp': (1.22, 1.24)}, {'text': 'HAVE', 'timestamp': (1.42, 1.58)}, {'text': 'A', 'timestamp': (1.66, 1.68)}, {'text': 'DREAM', 'timestamp': (1.76, 2.14)}, {'text': 'BUT', 'timestamp': (3.68, 3.8)}, {'text': 'ONE', 'timestamp': (3.94, 4.06)}, {'text': 'DAY', 'timestamp': (4.16, 4.3)}, {'text': 'THIS', 'timestamp': (6.36, 6.54)}, {'text': 'NATION', 'timestamp': (6.68, 7.1)}, {'text': 'WILL', 'timestamp': (7.32, 7.56)}, {'text': 'RISE', 'timestamp': (7.8, 8.26)}, {'text': 'UP', 'timestamp': (8.38, 8.48)}, {'text': 'AND', 'timestamp': (10.08, 10.18)}, {'text': 'LIVE', 'timestamp': (10.26, 10.48)}, {'text': 'OUT', 'timestamp': (10.58, 10.7)}, {'text': 'THE', 'timestamp': (10.82, 10.9)}, {'text': 'TRUE', 'timestamp': (10.98, 11.18)}, {'text': 'MEANING', 'timestamp': (11.26, 11.58)}, {'text': 'OF', 'timestamp': (11.66, 11.7)}, {'text': 'ITS', 'timestamp': (11.76, 11.88)}, {'text': 'CREED', 'timestamp': (12.0, 12.38)}]}
+```
+
+モデルは、テキストを推測し、文の中で各単語がいつ発音されたかを出力しました。
+
+各タスクごとに利用可能な多くのパラメータがありますので、何を調整できるかを確認するために各タスクのAPIリファレンスを確認してください!
+たとえば、[`~transformers.AutomaticSpeechRecognitionPipeline`]には、モデル単体では処理できない非常に長いオーディオファイル(たとえば、映画全体や1時間のビデオの字幕付けなど)で役立つ`chunk_length_s`パラメータがあります。
+
+
+
+役立つパラメータが見つからない場合は、[リクエスト](https://github.com/huggingface/transformers/issues/new?assignees=&labels=feature&template=feature-request.yml)してください!
+
+## Using pipeline in a dataset
+
+パイプラインは大規模なデータセット上で推論を実行することもできます。これを行う最も簡単な方法は、イテレータを使用することです:
+
+```py
+def data():
+ for i in range(1000):
+ yield f"My example {i}"
+
+
+pipe = pipeline(model="openai-community/gpt2", device=0)
+generated_characters = 0
+for out in pipe(data()):
+ generated_characters += len(out[0]["generated_text"])
+```
+
+イテレーター `data()` は各結果を生成し、パイプラインは自動的に入力が反復可能であることを認識し、データを取得し続けながらGPU上で処理を行います(これは[DataLoader](https://pytorch.org/docs/stable/data.html#torch.utils.data.DataLoader)を内部で使用しています)。
+これは、データセット全体にメモリを割り当てる必要がなく、GPUにできるだけ速くデータを供給できるため重要です。
+
+バッチ処理は処理を高速化できる可能性があるため、ここで`batch_size`パラメータを調整して試すことが役立つかもしれません。
+
+データセットを反復処理する最も簡単な方法は、🤗 [Datasets](https://github.com/huggingface/datasets/)からデータセットを読み込むことです:
+
+```py
+# KeyDataset is a util that will just output the item we're interested in.
+from transformers.pipelines.pt_utils import KeyDataset
+from datasets import load_dataset
+
+pipe = pipeline(model="hf-internal-testing/tiny-random-wav2vec2", device=0)
+dataset = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation[:10]")
+
+for out in pipe(KeyDataset(dataset, "audio")):
+ print(out)
+```
+
+## Using pipelines for a webserver
+
+
+推論エンジンを作成することは複雑なトピックで、独自のページが必要です。
+
+
+[リンク](./pipeline_webserver)
+
+## Vision pipeline
+
+ビジョンタスク用の[`pipeline`]を使用する方法はほぼ同じです。
+
+タスクを指定し、画像をクラシファイアに渡します。画像はリンク、ローカルパス、またはBase64エンコードされた画像であることができます。例えば、以下の画像はどの種類の猫ですか?
+
+
+
+```py
+>>> from transformers import pipeline
+
+>>> vision_classifier = pipeline(model="google/vit-base-patch16-224")
+>>> preds = vision_classifier(
+... images="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4335, 'label': 'lynx, catamount'}, {'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}, {'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}, {'score': 0.0239, 'label': 'Egyptian cat'}, {'score': 0.0229, 'label': 'tiger cat'}]
+```
+
+## Text pipeline
+
+[`pipeline`]を使用することは、NLPタスクに対してほぼ同じです。
+
+```py
+>>> from transformers import pipeline
+
+>>> # This model is a `zero-shot-classification` model.
+>>> # It will classify text, except you are free to choose any label you might imagine
+>>> classifier = pipeline(model="facebook/bart-large-mnli")
+>>> classifier(
+... "I have a problem with my iphone that needs to be resolved asap!!",
+... candidate_labels=["urgent", "not urgent", "phone", "tablet", "computer"],
+... )
+{'sequence': 'I have a problem with my iphone that needs to be resolved asap!!', 'labels': ['urgent', 'phone', 'computer', 'not urgent', 'tablet'], 'scores': [0.504, 0.479, 0.013, 0.003, 0.002]}
+```
+
+## Multimodal pipeline
+
+[`pipeline`]は、1つ以上のモダリティをサポートしています。たとえば、視覚的な質問応答(VQA)タスクはテキストと画像を組み合わせています。
+好きな画像リンクと画像に関する質問を自由に使ってください。画像はURLまたは画像のローカルパスで指定できます。
+
+例えば、この[請求書画像](https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png)を使用する場合:
+
+```py
+>>> from transformers import pipeline
+
+>>> vqa = pipeline(model="impira/layoutlm-document-qa")
+>>> output = vqa(
+... image="https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png",
+... question="What is the invoice number?",
+... )
+>>> output[0]["score"] = round(output[0]["score"], 3)
+>>> output
+[{'score': 0.425, 'answer': 'us-001', 'start': 16, 'end': 16}]
+```
+
+
+
+上記の例を実行するには、🤗 Transformersに加えて [`pytesseract`](https://pypi.org/project/pytesseract/) がインストールされている必要があります。
+
+```bash
+sudo apt install -y tesseract-ocr
+pip install pytesseract
+```
+
+
+
+## Using `pipeline` on large models with 🤗 `accelerate`:
+
+まず、`accelerate` を`pip install accelerate` でインストールしていることを確認してください。
+
+次に、`device_map="auto"` を使用してモデルをロードします。この例では `facebook/opt-1.3b` を使用します。
+
+```python
+# pip install accelerate
+import torch
+from transformers import pipeline
+
+pipe = pipeline(model="facebook/opt-1.3b", torch_dtype=torch.bfloat16, device_map="auto")
+output = pipe("これは素晴らしい例です!", do_sample=True, top_p=0.95)
+```
+
+もし `bitsandbytes` をインストールし、`load_in_8bit=True` 引数を追加すれば、8ビットで読み込まれたモデルを渡すこともできます。
+
+```py
+# pip install accelerate bitsandbytes
+import torch
+from transformers import pipeline
+
+pipe = pipeline(model="facebook/opt-1.3b", device_map="auto", model_kwargs={"load_in_8bit": True})
+output = pipe("This is a cool example!", do_sample=True, top_p=0.95)
+```
+
+注意: BLOOMなどの大規模モデルのロードをサポートするHugging Faceモデルのいずれかで、チェックポイントを置き換えることができます!
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/pipeline_webserver.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/pipeline_webserver.md
new file mode 100644
index 0000000000000000000000000000000000000000..3b35a01490d40912a5256cb42fb3f5ba2f789ab5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/pipeline_webserver.md
@@ -0,0 +1,132 @@
+
+
+# Webサーバー用のパイプラインの使用
+
+
+推論エンジンの作成は複雑なトピックであり、"最適な"ソリューションはおそらく問題の領域に依存するでしょう。CPUまたはGPUを使用していますか?最低のレイテンシ、最高のスループット、多くのモデルのサポート、または特定のモデルの高度な最適化を望んでいますか?
+このトピックに取り組むための多くの方法があり、私たちが紹介するのは、おそらく最適なソリューションではないかもしれないが、始めるための良いデフォルトです。
+
+
+重要なことは、Webサーバーはリクエストを待機し、受信したように扱うシステムであるため、[データセット](pipeline_tutorial#using-pipelines-on-a-dataset)のように、イテレータを使用できることです。
+
+通常、Webサーバーは並列処理(マルチスレッド、非同期など)されて、さまざまなリクエストを同時に処理します。一方、パイプライン(および主にその基礎となるモデル)は並列処理にはあまり適していません。それらは多くのRAMを使用するため、実行中に利用可能なリソースをすべて提供するか、計算集約型のジョブである場合に最適です。
+
+Webサーバーは受信と送信の軽い負荷を処理し、実際の作業を1つのスレッドで処理するようにします。この例では`starlette`を使用します。実際のフレームワークはあまり重要ではありませんが、別のフレームワークを使用している場合は、同じ効果を得るためにコードを調整または変更する必要があるかもしれません。
+
+`server.py`を作成してください:
+
+
+```py
+from starlette.applications import Starlette
+from starlette.responses import JSONResponse
+from starlette.routing import Route
+from transformers import pipeline
+import asyncio
+
+
+async def homepage(request):
+ payload = await request.body()
+ string = payload.decode("utf-8")
+ response_q = asyncio.Queue()
+ await request.app.model_queue.put((string, response_q))
+ output = await response_q.get()
+ return JSONResponse(output)
+
+
+async def server_loop(q):
+ pipe = pipeline(model="google-bert/bert-base-uncased")
+ while True:
+ (string, response_q) = await q.get()
+ out = pipe(string)
+ await response_q.put(out)
+
+
+app = Starlette(
+ routes=[
+ Route("/", homepage, methods=["POST"]),
+ ],
+)
+
+
+@app.on_event("startup")
+async def startup_event():
+ q = asyncio.Queue()
+ app.model_queue = q
+ asyncio.create_task(server_loop(q))
+```
+
+ここから始めることができます:
+```bash
+uvicorn server:app
+```
+
+そして、次のようにクエリできます:
+```bash
+curl -X POST -d "test [MASK]" http://localhost:8000/
+#[{"score":0.7742936015129089,"token":1012,"token_str":".","sequence":"test."},...]
+```
+
+
+
+そして、これでウェブサーバーを作成する方法の良いアイデアを持っています!
+
+本当に重要なのは、モデルを**一度だけ**ロードすることです。これにより、ウェブサーバー上にモデルのコピーがないため、不必要なRAMが使用されなくなります。
+その後、キューイングメカニズムを使用して、動的バッチ処理を行うなど、いくつかのアイテムを蓄積してから推論を行うなど、高度な処理を行うことができます:
+
+
+
+以下のコードサンプルは、可読性のために擬似コードのように書かれています。システムリソースに合理的かどうかを確認せずに実行しないでください!
+
+
+
+
+```py
+(string, rq) = await q.get()
+strings = []
+queues = []
+while True:
+ try:
+ (string, rq) = await asyncio.wait_for(q.get(), timeout=0.001) # 1ms
+ except asyncio.exceptions.TimeoutError:
+ break
+ strings.append(string)
+ queues.append(rq)
+strings
+outs = pipe(strings, batch_size=len(strings))
+for rq, out in zip(queues, outs):
+ await rq.put(out)
+```
+
+まず第一に、通常はあまり良いアイデアではないバッチサイズの制限がありません。次に、タイムアウトはキューの取得ごとにリセットされるため、推論を実行する前に1ms以上待つ可能性があります(最初のリクエストの遅延に1ms分遅れが生じます)。
+
+1msの締め切りを1回だけ持つのが良いでしょう。
+
+これは、キューに何もない場合でも常に1ms待機しますが、キューに何もない場合に推論を開始したい場合は適していないかもしれません。ただし、バッチ処理が本当に重要な場合には意味があるかもしれません。再度、1つの最適な解決策は存在しません。
+
+## Few things you might want to consider
+
+### Error checking
+
+本番環境では多くの問題が発生する可能性があります:メモリ不足、スペース不足、モデルの読み込みが失敗するかもしれません、クエリが誤っているかもしれません、クエリが正しい場合でもモデルの構成エラーのために実行に失敗するかもしれませんなど。
+
+一般的には、サーバーがエラーをユーザーに出力すると良いため、これらのエラーを表示するための多くの`try..except`ステートメントを追加することは良いアイデアです。ただし、セキュリティコンテキストに応じてこれらのエラーをすべて表示することはセキュリティリスクになる可能性があることに注意してください。
+
+### Circuit breaking
+
+Webサーバーは通常、過負荷時に正しいエラーを返す方が良いです。クエリを無期限に待つ代わりに適切なエラーを返します。長時間待つ代わりに503エラーを返すか、長時間待ってから504エラーを返すかです。
+
+提案されたコードでは単一のキューがあるため、キューサイズを見ることは、Webサーバーが負荷に耐える前にエラーを返すための基本的な方法です。
+
+### Blocking the main thread
+
+現在、PyTorchは非同期を認識していないため、計算はメインスレッドをブロックします。つまり、PyTorchが独自のスレッド/プロセスで実行されるようにすると良いでしょう。提案されたコードは、スレッドと非同期とキューがうまく連携しないため、これは行われていませんが、最終的には同じことを行います。
+
+これは、単一のアイテムの推論が長い場合(>1秒)に重要です。この場合、推論中にすべてのクエリが1秒待たなければならないことを意味します。
+
+### Dynamic batching
+
+一般的に、バッチ処理は1回のアイテムを1回渡すよりも改善されることは必ずしもありません(詳細は[バッチ処理の詳細](./main_classes/pipelines#pipeline-batching)を参照)。しかし、正しい設定で使用すると非常に効果的です。APIではデフォルトで動的バッチ処理は行われません(遅延の機会が多すぎます)。しかし、非常に大規模なモデルであるBLOOM推論の場合、動的バッチ処理は**重要**です。これにより、すべてのユーザーにとってまともなエクスペリエンスを提供できます。
+
+以上が、提供されたテキストのMarkdown形式の翻訳です。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/pr_checks.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/pr_checks.md
new file mode 100644
index 0000000000000000000000000000000000000000..dc8450b52502e670c12cf4baeb0f0777395df15f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/pr_checks.md
@@ -0,0 +1,208 @@
+
+
+
+# Checks on a Pull Request
+
+🤗 Transformersリポジトリでプルリクエストを開くと、追加しているパッチが既存のものを壊していないことを確認するために、かなりの数のチェックが実行されます。これらのチェックには、次の4つのタイプがあります:
+- 通常のテスト
+- ドキュメンテーションのビルド
+- コードとドキュメンテーションのスタイル
+- リポジトリ全体の一貫性
+
+このドキュメントでは、これらのさまざまなチェックとその背後にある理由、そしてそれらのいずれかがあなたのプルリクエストで失敗した場合のローカルでのデバッグ方法について説明します。
+
+なお、理想的には、開発者用のインストールが必要です:
+
+
+```bash
+pip install transformers[dev]
+```
+
+または編集可能なインストールの場合:
+
+
+```bash
+pip install -e .[dev]
+```
+
+トランスフォーマーズのリポジトリ内で作業しています。トランスフォーマーズのオプションの依存関係の数が増えたため、すべてを取得できない可能性があります。開発用インストールが失敗した場合、作業しているディープラーニングフレームワーク(PyTorch、TensorFlow、および/またはFlax)をインストールし、次の手順を実行してください。
+
+
+```bash
+pip install transformers[quality]
+```
+
+または編集可能なインストールの場合:
+
+```bash
+pip install -e .[quality]
+```
+
+## Tests
+
+`ci/circleci: run_tests_` で始まるすべてのジョブは、Transformersのテストスイートの一部を実行します。これらのジョブは、特定の環境でライブラリの一部に焦点を当てて実行されます。たとえば、`ci/circleci: run_tests_pipelines_tf` は、TensorFlowのみがインストールされた環境でパイプラインのテストを実行します。
+
+テストスイートの一部のみが実行されるように注意してください。テストスイートは、変更前と変更後のPRのライブラリの違いを決定し、その違いに影響を受けるテストを選択するためのユーティリティが実行されます。このユーティリティは、ローカルで以下のコマンドを実行して実行できます:
+
+
+```bash
+python utils/tests_fetcher.py
+```
+
+1. リポジトリのルートからスクリプトを実行します。これは次のステップを実行します:
+
+ 1. 差分内の各ファイルをチェックし、変更がコード内にあるか、コメントやドキュメンテーション文字列のみにあるかを確認します。実際のコード変更があるファイルのみを保持します。
+
+ 2. 内部のマップを構築します。このマップは、ライブラリのソースコードの各ファイルが再帰的に影響を与えるすべてのファイルを提供します。モジュールAがモジュールBに影響を与えるとは、モジュールBがモジュールAをインポートする場合を指します。再帰的な影響を得るには、モジュールAからモジュールBへのモジュールのチェーンが必要で、各モジュールは前のモジュールをインポートする必要があります。
+
+ 3. このマップをステップ1で収集したファイルに適用します。これにより、PRに影響を受けるモデルファイルのリストが得られます。
+
+ 4. これらのファイルをそれに対応するテストファイルにマップし、実行するテストのリストを取得します。
+
+2. スクリプトをローカルで実行する場合、ステップ1、3、および4の結果が表示され、実行するテストがわかります。スクリプトはまた、`test_list.txt` という名前のファイルを作成します。このファイルには実行するテストのリストが含まれており、次のコマンドでローカルで実行できます:
+
+```bash
+python -m pytest -n 8 --dist=loadfile -rA -s $(cat test_list.txt)
+```
+
+## Documentation build
+
+`build_pr_documentation` ジョブは、ドキュメンテーションのビルドを行い、あなたのPRがマージされた後にすべてが正常に表示されることを確認します。ボットがプレビューのドキュメンテーションへのリンクをPRに追加します。PRに対する変更は、プレビューに自動的に反映されます。ドキュメンテーションのビルドに失敗した場合、失敗したジョブの隣にある「詳細」をクリックして、何が問題になっているかを確認できます。多くの場合、問題は`toctree`内のファイルが不足しているなど、単純なものです。
+
+ドキュメンテーションをローカルでビルドまたはプレビューしたい場合は、[docsフォルダ内の`README.md`](https://github.com/huggingface/transformers/tree/main/docs)をご覧ください。
+
+## Code and documentation style
+
+すべてのソースファイル、例、テストには、`black`と`ruff`を使用してコードのフォーマットが適用されます。また、ドックストリングと`rst`ファイルのフォーマット、Transformersの`__init__.py`ファイルで実行される遅延インポートの順序についてもカスタムツールが存在します(`utils/style_doc.py`と`utils/custom_init_isort.py`)。これらすべては、以下を実行することで起動できます。
+
+
+```bash
+make style
+```
+
+CIは、`ci/circleci: check_code_quality` チェック内でこれらのチェックが適用されていることを確認します。また、`ruff` を実行し、未定義の変数や使用されていない変数がある場合にエラーを報告します。このチェックをローカルで実行するには、以下のコマンドを使用してください。
+
+
+```bash
+make quality
+```
+
+時間がかかることがあります。したがって、現在のブランチで変更したファイルのみで同じことを実行するには、次のコマンドを実行します。
+
+
+```bash
+make fixup
+```
+
+この最後のコマンドは、リポジトリの整合性のためのすべての追加のチェックも実行します。それらを詳しく見てみましょう。
+
+## Repository consistency
+
+これには、あなたのPRがリポジトリを適切な状態に保ったままであることを確認するためのすべてのテストが含まれており、ci/`circleci: check_repository_consistency` チェックによって実行されます。ローカルでこのチェックを実行するには、以下を実行します。
+
+```bash
+make repo-consistency
+```
+
+これを確認します:
+
+- `utils/check_repo.py` によって実行される、init に追加されたすべてのオブジェクトが文書化されています。
+- `utils/check_inits.py` によって実行される、すべての `__init__.py` ファイルがその2つのセクションで同じ内容を持っています。
+- `utils/check_copies.py` によって実行される、他のモジュールからのコピーとして識別されたすべてのコードが元のコードと一致しています。
+- `utils/check_config_docstrings.py` によって実行される、すべての設定クラスには少なくとも1つの有効なチェックポイントがドキュメント文字列に記載されています。
+- `utils/check_config_attributes.py` によって実行される、すべての設定クラスには、対応するモデリングファイルで使用されている属性のみが含まれています。
+- `utils/check_copies.py` によって実行される、README とドキュメントのインデックスの翻訳が、メインのREADME と同じモデルリストを持っています。
+- `utils/check_table.py` によって実行される、ドキュメンテーションの自動生成テーブルが最新であることを確認します。
+- `utils/check_dummies.py` によって実行される、すべてのオブジェクトが利用可能であり、オプションの依存関係がすべてインストールされていなくても問題ありません。
+
+このチェックが失敗する場合、最初の2つの項目は手動で修正する必要があり、最後の4つはコマンドを実行して自動的に修正できます。
+
+
+```bash
+make fix-copies
+```
+
+追加のチェックポイントは、新しいモデルを追加するPull Request(PR)に関連しています。主に次の点を確認します:
+
+- すべての追加されたモデルは、Auto-mapping(`utils/check_repo.py`で実行)に含まれています。
+
+- すべてのモデルが適切にテストされています(`utils/check_repo.py`で実行)。
+
+
+
+
+### Check copies
+
+Transformersライブラリは、モデルコードに関して非常に意見があるため、各モデルは他のモデルに依存せずに完全に1つのファイルに実装する必要があります。したがって、特定のモデルのコードのコピーが元のコードと一貫しているかどうかを確認する仕組みを追加しました。これにより、バグ修正がある場合、他の影響を受けるモデルをすべて確認し、変更を伝達するかコピーを破棄するかを選択できます。
+
+
+
+ファイルが別のファイルの完全なコピーである場合、それを`utils/check_copies.py`の`FULL_COPIES`定数に登録する必要があります。
+
+
+
+この仕組みは、`# Copied from xxx`という形式のコメントに依存しています。`xxx`は、コピーされているクラスまたは関数の完全なパスを含む必要があります。例えば、`RobertaSelfOutput`は`BertSelfOutput`クラスの直接のコピーですので、[こちら](https://github.com/huggingface/transformers/blob/2bd7a27a671fd1d98059124024f580f8f5c0f3b5/src/transformers/models/roberta/modeling_roberta.py#L289)にコメントがあります。
+
+
+```py
+# Copied from transformers.models.bert.modeling_bert.BertSelfOutput
+```
+
+注意点として、これをクラス全体に適用する代わりに、コピー元の関連メソッドに適用できます。たとえば、[こちら](https://github.com/huggingface/transformers/blob/2bd7a27a671fd1d98059124024f580f8f5c0f3b5/src/transformers/models/roberta/modeling_roberta.py#L598)では、`RobertaPreTrainedModel._init_weights` が `BertPreTrainedModel` からコピーされており、以下のコメントがあります:
+
+
+```py
+# Copied from transformers.models.bert.modeling_bert.BertAttention with Bert->Roberta
+```
+
+注:矢印の周りにはスペースが含まれていてはいけません(もちろん、そのスペースが置換パターンの一部である場合を除きます)。
+
+カンマで区切られた複数のパターンを追加できます。例えば、ここでは `CamemberForMaskedLM` は `RobertaForMaskedLM` の直接のコピーで、2つの置換があります: `Roberta` から `Camembert` へ、そして `ROBERTA` から `CAMEMBERT` へと置換されます。[こちら](https://github.com/huggingface/transformers/blob/15082a9dc6950ecae63a0d3e5060b2fc7f15050a/src/transformers/models/camembert/modeling_camembert.py#L929)で、この作業はコメント付きで行われています。
+
+
+```py
+# Copied from transformers.models.roberta.modeling_roberta.RobertaForMaskedLM with Roberta->Camembert, ROBERTA->CAMEMBERT
+```
+
+
+もし順序が重要な場合(以前の置換と競合する可能性があるため)、置換は左から右に実行されます。
+
+
+
+もし置換がフォーマットを変更する場合(たとえば、短い名前を非常に長い名前に置き換える場合など)、自動フォーマッタを適用した後にコピーが確認されます。
+
+
+
+パターンが同じ置換の異なるケース(大文字と小文字のバリアントがある)の場合、オプションとして `all-casing` を追加するだけの別の方法もあります。[こちら](https://github.com/huggingface/transformers/blob/15082a9dc6950ecae63a0d3e5060b2fc7f15050a/src/transformers/models/mobilebert/modeling_mobilebert.py#L1237)は、`MobileBertForSequenceClassification` 内の例で、コメントがついています。
+
+
+```py
+# Copied from transformers.models.bert.modeling_bert.BertForSequenceClassification with Bert->MobileBert all-casing
+```
+
+この場合、コードは「BertForSequenceClassification」からコピーされ、次のように置換されます:
+- `Bert` を `MobileBert` に置き換える(例:`init`で `MobileBertModel` を使用する場合)
+- `bert` を `mobilebert` に置き換える(例:`self.mobilebert` を定義する場合)
+- `BERT` を `MOBILEBERT` に置き換える(定数 `MOBILEBERT_INPUTS_DOCSTRING` 内で)
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/preprocessing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/preprocessing.md
new file mode 100644
index 0000000000000000000000000000000000000000..ea0b98df028031e15f985cf53df53ca49b45891b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/preprocessing.md
@@ -0,0 +1,533 @@
+
+
+# Preprocess
+
+[[open-in-colab]]
+
+データセットでモデルをトレーニングする前に、それをモデルの期待する入力形式に前処理する必要があります。
+データがテキスト、画像、またはオーディオであるかどうかにかかわらず、それらはテンソルのバッチに変換して組み立てる必要があります。
+🤗 Transformersは、データをモデル用に準備するのに役立つ前処理クラスのセットを提供しています。
+このチュートリアルでは、次のことを学びます:
+
+* テキストの場合、[Tokenizer](./main_classes/tokenizer)を使用してテキストをトークンのシーケンスに変換し、トークンの数値表現を作成し、それらをテンソルに組み立てる方法。
+* 音声とオーディオの場合、[Feature extractor](./main_classes/feature_extractor)を使用してオーディオ波形から連続的な特徴を抽出し、それらをテンソルに変換する方法。
+* 画像入力の場合、[ImageProcessor](./main_classes/image)を使用して画像をテンソルに変換する方法。
+* マルチモーダル入力の場合、[Processor](./main_classes/processors)を使用してトークナイザと特徴抽出器または画像プロセッサを組み合わせる方法。
+
+
+
+`AutoProcessor`は常に動作し、使用するモデルに適切なクラスを自動的に選択します。
+トークナイザ、画像プロセッサ、特徴抽出器、またはプロセッサを使用しているかにかかわらず、動作します。
+
+
+
+始める前に、🤗 Datasetsをインストールして、いくつかのデータセットを試すことができるようにしてください:
+
+```bash
+pip install datasets
+```
+
+## Natural Language Processing
+
+
+
+事前学習済みモデルを使用する予定の場合、関連する事前学習済みトークナイザを使用することが重要です。これにより、テキストが事前学習コーパスと同じ方法で分割され、事前学習中に通常*ボキャブ*として参照される対応するトークンインデックスを使用します。
+
+
+
+[`AutoTokenizer.from_pretrained`]メソッドを使用して事前学習済みトークナイザをロードして、開始しましょう。これにより、モデルが事前学習された*ボキャブ*がダウンロードされます:
+
+```python
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
+```
+
+次に、テキストをトークナイザに渡します:
+
+```py
+>>> encoded_input = tokenizer("Do not meddle in the affairs of wizards, for they are subtle and quick to anger.")
+>>> print(encoded_input)
+{'input_ids': [101, 2079, 2025, 19960, 10362, 1999, 1996, 3821, 1997, 16657, 1010, 2005, 2027, 2024, 11259, 1998, 4248, 2000, 4963, 1012, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+トークナイザは、重要な3つの項目を持つ辞書を返します:
+
+* [input_ids](glossary#input-ids) は文中の各トークンに対応するインデックスです。
+* [attention_mask](glossary#attention-mask) はトークンがアテンションを受ける必要があるかどうかを示します。
+* [token_type_ids](glossary#token-type-ids) は複数のシーケンスがある場合、トークンがどのシーケンスに属しているかを識別します。
+
+`input_ids` をデコードして入力を返します:
+
+```python
+>>> tokenizer.decode(encoded_input["input_ids"])
+'[CLS] 魔法使いの事に干渉するな、彼らは微妙で怒りっぽい。 [SEP]'
+```
+
+如何にお分かりいただけるかと思いますが、トークナイザはこの文章に2つの特別なトークン、`CLS`(クラシファイア)と`SEP`(セパレータ)を追加しました。
+すべてのモデルが特別なトークンを必要とするわけではありませんが、必要な場合、トークナイザは自動的にそれらを追加します。
+
+複数の文章を前処理する場合、トークナイザにリストとして渡してください:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_inputs = tokenizer(batch_sentences)
+>>> print(encoded_inputs)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1]]}
+```
+
+### Pad
+
+文章は常に同じ長さではないことがあり、これはテンソル(モデルの入力)が均一な形状を持つ必要があるため問題となります。
+パディングは、短い文に特別な「パディングトークン」を追加して、テンソルを長いシーケンスに合わせるための戦略です。
+
+バッチ内の短いシーケンスを最長のシーケンスに合わせるために、`padding`パラメータを`True`に設定します:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True)
+>>> print(encoded_input)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
+```
+
+1番目と3番目の文は、短いために`0`でパディングされています。
+
+### Truncation
+
+逆のスペクトルでは、時折、モデルが処理するのに長すぎるシーケンスがあるかもしれません。この場合、シーケンスを短縮する必要があります。
+
+モデルが受け入れる最大の長さにシーケンスを切り詰めるには、`truncation`パラメータを`True`に設定します:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True)
+>>> print(encoded_input)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
+```
+
+
+
+異なるパディングと切り詰めの引数について詳しくは、[パディングと切り詰め](./pad_truncation)のコンセプトガイドをご覧ください。
+
+
+
+### Build tensors
+
+最後に、トークナイザがモデルに供給される実際のテンソルを返すように設定します。
+
+`return_tensors`パラメータを`pt`(PyTorch用)または`tf`(TensorFlow用)に設定します:
+
+
+
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True, return_tensors="pt")
+>>> print(encoded_input)
+{'input_ids': tensor([[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]]),
+ 'token_type_ids': tensor([[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]]),
+ 'attention_mask': tensor([[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]])}
+```
+
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True, return_tensors="tf")
+>>> print(encoded_input)
+{'input_ids': ,
+ 'token_type_ids': ,
+ 'attention_mask': }
+```
+
+
+
+## Audio
+
+オーディオタスクの場合、データセットをモデル用に準備するために[特徴抽出器](main_classes/feature_extractor)が必要です。
+特徴抽出器は生のオーディオデータから特徴を抽出し、それらをテンソルに変換するために設計されています。
+
+[PolyAI/minds14](https://huggingface.co/datasets/PolyAI/minds14)データセットをロードして(データセットのロード方法の詳細については🤗 [Datasetsチュートリアル](https://huggingface.co/docs/datasets/load_hub)を参照)、
+オーディオデータセットで特徴抽出器をどのように使用できるかを確認してみましょう:
+
+```python
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train")
+```
+
+アクセスして`audio`列の最初の要素を確認します。`audio`列を呼び出すと、自動的にオーディオファイルが読み込まれ、リサンプリングされます:
+
+```py
+>>> dataset[0]["audio"]
+{'array': array([ 0. , 0.00024414, -0.00024414, ..., -0.00024414,
+ 0. , 0. ], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~JOINT_ACCOUNT/602ba55abb1e6d0fbce92065.wav',
+ 'sampling_rate': 8000}
+```
+
+これにより、3つのアイテムが返されます:
+
+* `array` は読み込まれた音声信号で、1Dの配列として読み込まれます。必要に応じてリサンプリングされることもあります。
+* `path` は音声ファイルの場所を指します。
+* `sampling_rate` は音声信号内のデータポイントが1秒間にいくつ測定されるかを示します。
+
+このチュートリアルでは、[Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base)モデルを使用します。
+モデルカードを確認すると、Wav2Vec2が16kHzのサンプリングされた音声オーディオで事前学習されていることがわかります。
+モデルの事前学習に使用されたデータセットのサンプリングレートと、あなたのオーディオデータのサンプリングレートが一致することが重要です。
+データのサンプリングレートが異なる場合、データをリサンプリングする必要があります。
+
+1. 🤗 Datasetsの [`~datasets.Dataset.cast_column`] メソッドを使用して、サンプリングレートを16kHzにアップサンプリングします:
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16_000))
+```
+
+2. 再び `audio` 列を呼び出してオーディオファイルをリサンプルします:
+
+```py
+>>> dataset[0]["audio"]
+{'array': array([ 2.3443763e-05, 2.1729663e-04, 2.2145823e-04, ...,
+ 3.8356509e-05, -7.3497440e-06, -2.1754686e-05], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~JOINT_ACCOUNT/602ba55abb1e6d0fbce92065.wav',
+ 'sampling_rate': 16000}
+```
+
+次に、入力を正規化しパディングするために特徴抽出器をロードします。テキストデータをパディングする場合、短いシーケンスには `0` が追加されます。同じ考え方がオーディオデータにも適用されます。特徴抽出器は `array` に `0` を追加します(これは無音として解釈されます)。
+
+[`AutoFeatureExtractor.from_pretrained`]を使用して特徴抽出器をロードします:
+
+```python
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base")
+```
+
+オーディオ `array` を特徴抽出器に渡します。特徴抽出器で発生する可能性のある無音エラーをより良くデバッグするために、特徴抽出器に `sampling_rate` 引数を追加することをお勧めします。
+
+```python
+>>> audio_input = [dataset[0]["audio"]["array"]]
+>>> feature_extractor(audio_input, sampling_rate=16000)
+{'input_values': [array([ 3.8106556e-04, 2.7506407e-03, 2.8015103e-03, ...,
+ 5.6335266e-04, 4.6588284e-06, -1.7142107e-04], dtype=float32)]}
+```
+
+同様に、トークナイザと同様に、バッチ内の可変シーケンスを処理するためにパディングまたは切り詰めを適用できます。次に、これらの2つのオーディオサンプルのシーケンス長を確認してみましょう:
+
+```python
+>>> dataset[0]["audio"]["array"].shape
+(173398,)
+
+>>> dataset[1]["audio"]["array"].shape
+(106496,)
+```
+
+この関数は、データセットを前処理してオーディオサンプルの長さを同じにするためのものです。最大サンプル長を指定し、特徴抽出器はシーケンスをそれに合わせてパディングまたは切り詰めます。
+
+```py
+>>> def preprocess_function(examples):
+... audio_arrays = [x["array"] for x in examples["audio"]]
+... inputs = feature_extractor(
+... audio_arrays,
+... sampling_rate=16000,
+... padding=True,
+... max_length=100000,
+... truncation=True,
+... )
+... return inputs
+```
+
+`preprocess_function`をデータセットの最初の数例に適用します:
+
+```python
+>>> processed_dataset = preprocess_function(dataset[:5])
+```
+
+サンプルの長さは現在同じで、指定された最大長と一致しています。これで処理されたデータセットをモデルに渡すことができます!
+
+```py
+>>> processed_dataset["input_values"][0].shape
+(100000,)
+
+>>> processed_dataset["input_values"][1].shape
+(100000,)
+```
+
+## Computer Vision
+
+コンピュータビジョンタスクでは、モデル用にデータセットを準備するための[画像プロセッサ](main_classes/image_processor)が必要です。
+画像の前処理には、画像をモデルが期待する入力形式に変換するためのいくつかのステップが含まれています。これらのステップには、リサイズ、正規化、カラーチャネルの補正、および画像をテンソルに変換するなどが含まれます。
+
+
+
+画像の前処理は、通常、画像の増強の形式に従います。画像の前処理と画像の増強の両方は画像データを変換しますが、異なる目的があります:
+
+* 画像の増強は、過学習を防ぎ、モデルの堅牢性を向上させるのに役立つ方法で画像を変更します。データを増強する方法は無限で、明るさや色の調整、クロップ、回転、リサイズ、ズームなど、様々な方法があります。ただし、増強操作によって画像の意味が変わらないように注意する必要があります。
+* 画像の前処理は、画像がモデルの期待する入力形式と一致することを保証します。コンピュータビジョンモデルをファインチューニングする場合、画像はモデルが最初にトレーニングされたときとまったく同じ方法で前処理する必要があります。
+
+画像の増強には任意のライブラリを使用できます。画像の前処理には、モデルに関連付けられた`ImageProcessor`を使用します。
+
+
+
+コンピュータビジョンのデータセットで画像プロセッサを使用する方法を示すために、[food101](https://huggingface.co/datasets/food101)データセットをロードします(データセットのロード方法の詳細については🤗[Datasetsチュートリアル](https://huggingface.co/docs/datasets/load_hub)を参照):
+
+
+
+データセットがかなり大きいため、🤗 Datasetsの`split`パラメータを使用してトレーニングデータの小さなサンプルのみをロードします!
+
+
+
+```python
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("food101", split="train[:100]")
+```
+
+次に、🤗 Datasetsの [`Image`](https://huggingface.co/docs/datasets/package_reference/main_classes?highlight=image#datasets.Image) 機能で画像を見てみましょう:
+
+```python
+>>> dataset[0]["image"]
+```
+
+
+
+
+
+上記の例では、画像のサイズ変更を既に画像増強変換で行っているため、`do_resize=False`を設定しました。
+適切な `image_processor` からの `size` 属性を活用しています。画像増強中に画像のサイズ変更を行わない場合は、このパラメータを省略してください。
+デフォルトでは、`ImageProcessor` がサイズ変更を処理します。
+
+画像を増強変換の一部として正規化したい場合は、`image_processor.image_mean` と `image_processor.image_std` の値を使用してください。
+
+
+3. 次に、🤗 Datasetsの[`set_transform`](https://huggingface.co/docs/datasets/process#format-transform)を使用して、変換をリアルタイムで適用します:
+
+```python
+>>> dataset.set_transform(transforms)
+```
+
+4. 画像にアクセスすると、画像プロセッサが `pixel_values` を追加したことがわかります。これで処理済みのデータセットをモデルに渡すことができます!
+
+```python
+>>> dataset[0].keys()
+```
+
+以下は、変換が適用された後の画像の外観です。 画像はランダムに切り抜かれ、その色の特性も異なります。
+
+```py
+>>> import numpy as np
+>>> import matplotlib.pyplot as plt
+
+>>> img = dataset[0]["pixel_values"]
+>>> plt.imshow(img.permute(1, 2, 0))
+```
+
+
+
+
+
+オブジェクト検出、意味セグメンテーション、インスタンスセグメンテーション、およびパノプティックセグメンテーションなどのタスクの場合、`ImageProcessor`は
+ポスト処理メソッドを提供します。これらのメソッドは、モデルの生の出力を境界ボックスやセグメンテーションマップなどの意味のある予測に変換します。
+
+
+
+### Pad
+
+一部の場合、たとえば、[DETR](./model_doc/detr)をファインチューニングする場合、モデルはトレーニング時にスケールの変更を適用します。
+これにより、バッチ内の画像のサイズが異なる場合があります。[`DetrImageProcessor`]から[`DetrImageProcessor.pad`]を使用し、
+カスタムの`collate_fn`を定義して画像を一緒にバッチ処理できます。
+
+```py
+>>> def collate_fn(batch):
+... pixel_values = [item["pixel_values"] for item in batch]
+... encoding = image_processor.pad(pixel_values, return_tensors="pt")
+... labels = [item["labels"] for item in batch]
+... batch = {}
+... batch["pixel_values"] = encoding["pixel_values"]
+... batch["pixel_mask"] = encoding["pixel_mask"]
+... batch["labels"] = labels
+... return batch
+```
+
+## Multi Modal
+
+マルチモーダル入力を使用するタスクの場合、モデル用にデータセットを準備するための[プロセッサ](main_classes/processors)が必要です。プロセッサは、トークナイザや特徴量抽出器などの2つの処理オブジェクトを結合します。
+
+自動音声認識(ASR)のためのプロセッサの使用方法を示すために、[LJ Speech](https://huggingface.co/datasets/lj_speech)データセットをロードします(データセットのロード方法の詳細については🤗 [Datasets チュートリアル](https://huggingface.co/docs/datasets/load_hub)を参照):
+
+```python
+>>> from datasets import load_dataset
+
+>>> lj_speech = load_dataset("lj_speech", split="train")
+```
+
+ASR(自動音声認識)の場合、主に `audio` と `text` に焦点を当てているため、他の列を削除できます:
+
+```python
+>>> lj_speech = lj_speech.map(remove_columns=["file", "id", "normalized_text"])
+```
+
+次に、`audio`と`text`の列を見てみましょう:
+
+```python
+>>> lj_speech[0]["audio"]
+{'array': array([-7.3242188e-04, -7.6293945e-04, -6.4086914e-04, ...,
+ 7.3242188e-04, 2.1362305e-04, 6.1035156e-05], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/917ece08c95cf0c4115e45294e3cd0dee724a1165b7fc11798369308a465bd26/LJSpeech-1.1/wavs/LJ001-0001.wav',
+ 'sampling_rate': 22050}
+
+>>> lj_speech[0]["text"]
+'Printing, in the only sense with which we are at present concerned, differs from most if not from all the arts and crafts represented in the Exhibition'
+```
+
+常に、オーディオデータセットのサンプリングレートを、モデルの事前学習に使用されたデータセットのサンプリングレートと一致させるように[リサンプル](preprocessing#audio)する必要があります!
+
+```py
+>>> lj_speech = lj_speech.cast_column("audio", Audio(sampling_rate=16_000))
+```
+
+プロセッサを [`AutoProcessor.from_pretrained`] を使用してロードします:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base-960h")
+```
+
+1. `array`内に含まれるオーディオデータを`input_values`に処理し、`text`を`labels`にトークン化する関数を作成します:
+
+```py
+>>> def prepare_dataset(example):
+... audio = example["audio"]
+
+... example.update(processor(audio=audio["array"], text=example["text"], sampling_rate=16000))
+
+... return example
+```
+
+2. サンプルに`prepare_dataset`関数を適用します:
+
+```py
+>>> prepare_dataset(lj_speech[0])
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/quicktour.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/quicktour.md
new file mode 100644
index 0000000000000000000000000000000000000000..0eb00cf220b54ab6c9f407564d5f1053461cdf51
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/quicktour.md
@@ -0,0 +1,588 @@
+
+
+# Quick tour
+
+[[open-in-colab]]
+
+🤗 Transformersを使い始めましょう! 開発者であろうと、日常的なユーザーであろうと、このクイックツアーは
+初めて始めるのを支援し、[`pipeline`]を使った推論方法、[AutoClass](./model_doc/auto)で事前学習済みモデルとプリプロセッサをロードする方法、
+そしてPyTorchまたはTensorFlowで素早くモデルをトレーニングする方法を示します。 初心者の場合、ここで紹介されたコンセプトの詳細な説明を提供する
+チュートリアルまたは[コース](https://huggingface.co/course/chapter1/1)を次に参照することをお勧めします。
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください:
+
+```bash
+!pip install transformers datasets evaluate accelerate
+```
+
+あなたはまた、好きな機械学習フレームワークをインストールする必要があります:
+
+
+
+
+```bash
+pip install torch
+```
+
+
+
+```bash
+pip install tensorflow
+```
+
+
+
+## Pipeline
+
+
+
+使用可能なタスクの完全な一覧については、[pipeline API リファレンス](./main_classes/pipelines)を確認してください。
+
+
+
+| **タスク** | **説明** | **モダリティ** | **パイプライン識別子** |
+|------------------------------|--------------------------------------------------------------------------------------------------------------|-----------------|-----------------------------------------------|
+| テキスト分類 | テキストのシーケンスにラベルを割り当てる | NLP | pipeline(task="sentiment-analysis") |
+| テキスト生成 | プロンプトを指定してテキストを生成する | NLP | pipeline(task="text-generation") |
+| 要約 | テキストまたはドキュメントの要約を生成する | NLP | pipeline(task="summarization") |
+| 画像分類 | 画像にラベルを割り当てる | コンピュータビジョン | pipeline(task="image-classification") |
+| 画像セグメンテーション | 画像の各個別のピクセルにラベルを割り当てる(セマンティック、パノプティック、およびインスタンスセグメンテーションをサポート) | コンピュータビジョン | pipeline(task="image-segmentation") |
+| オブジェクト検出 | 画像内のオブジェクトの境界ボックスとクラスを予測する | コンピュータビジョン | pipeline(task="object-detection") |
+| オーディオ分類 | オーディオデータにラベルを割り当てる | オーディオ | pipeline(task="audio-classification") |
+| 自動音声認識 | 音声をテキストに変換する | オーディオ | pipeline(task="automatic-speech-recognition") |
+| ビジュアルクエスチョン応答 | 画像と質問が与えられた場合に、画像に関する質問に回答する | マルチモーダル | pipeline(task="vqa") |
+| ドキュメントクエスチョン応答 | ドキュメントと質問が与えられた場合に、ドキュメントに関する質問に回答する | マルチモーダル | pipeline(task="document-question-answering") |
+| 画像キャプショニング | 与えられた画像にキャプションを生成する | マルチモーダル | pipeline(task="image-to-text") |
+
+まず、[`pipeline`] のインスタンスを作成し、使用したいタスクを指定します。
+このガイドでは、センチメント分析のために [`pipeline`] を使用する例を示します:
+
+```python
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("sentiment-analysis")
+```
+
+[`pipeline`]は、感情分析のためのデフォルトの[事前学習済みモデル](https://huggingface.co/distilbert/distilbert-base-uncased-finetuned-sst-2-english)とトークナイザをダウンロードしてキャッシュし、使用できるようになります。
+これで、`classifier`を対象のテキストに使用できます:
+
+```python
+>>> classifier("私たちは🤗 Transformersライブラリをお見せできてとても嬉しいです。")
+[{'label': 'POSITIVE', 'score': 0.9998}]
+```
+
+複数の入力がある場合は、[`pipeline`]に入力をリストとして渡して、辞書のリストを返します:
+
+```py
+>>> results = classifier(["🤗 Transformersライブラリをご紹介できて非常に嬉しいです。", "嫌いにならないでほしいです。"])
+>>> for result in results:
+... print(f"label: {result['label']}, スコア: {round(result['score'], 4)}")
+label: POSITIVE, スコア: 0.9998
+label: NEGATIVE, スコア: 0.5309
+```
+
+[`pipeline`]は、任意のタスクに対してデータセット全体を繰り返し処理することもできます。この例では、自動音声認識をタスクとして選びましょう:
+
+```python
+>>> import torch
+>>> from transformers import pipeline
+
+>>> speech_recognizer = pipeline("automatic-speech-recognition", model="facebook/wav2vec2-base-960h")
+```
+
+オーディオデータセットをロードします(詳細については🤗 Datasets [クイックスタート](https://huggingface.co/docs/datasets/quickstart#audio)を参照してください)。
+たとえば、[MInDS-14](https://huggingface.co/datasets/PolyAI/minds14)データセットをロードします:
+
+```python
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train") # doctest: +IGNORE_RESULT
+```
+
+データセットのサンプリングレートが[`facebook/wav2vec2-base-960h`](https://huggingface.co/facebook/wav2vec2-base-960h)がトレーニングされたサンプリングレートと一致することを確認してください:
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=speech_recognizer.feature_extractor.sampling_rate))
+```
+
+"audio"列を呼び出すと、オーディオファイルは自動的にロードされ、リサンプリングされます。最初の4つのサンプルから生の波形配列を抽出し、それをパイプラインにリストとして渡します。
+
+```py
+>>> result = speech_recognizer(dataset[:4]["audio"])
+>>> print([d["text"] for d in result])
+['I WOULD LIKE TO SET UP A JOINT ACCOUNT WITH MY PARTNER HOW DO I PROCEED WITH DOING THAT', "FONDERING HOW I'D SET UP A JOIN TO HELL T WITH MY WIFE AND WHERE THE AP MIGHT BE", "I I'D LIKE TOY SET UP A JOINT ACCOUNT WITH MY PARTNER I'M NOT SEEING THE OPTION TO DO IT ON THE APSO I CALLED IN TO GET SOME HELP CAN I JUST DO IT OVER THE PHONE WITH YOU AND GIVE YOU THE INFORMATION OR SHOULD I DO IT IN THE AP AN I'M MISSING SOMETHING UQUETTE HAD PREFERRED TO JUST DO IT OVER THE PHONE OF POSSIBLE THINGS", 'HOW DO I FURN A JOINA COUT']
+```
+
+大規模なデータセットで、入力が大きい場合(音声や画像など)、すべての入力をメモリに読み込む代わりに、リストではなくジェネレータを渡すことがお勧めです。詳細については[パイプラインAPIリファレンス](./main_classes/pipelines)を参照してください。
+
+### Use another model and tokenizer in the pipeline
+
+[`pipeline`]は[Hub](https://huggingface.co/models)からの任意のモデルを収容でき、他のユースケースに[`pipeline`]を適応させることが容易です。たとえば、フランス語のテキストを処理できるモデルが必要な場合、Hubのタグを使用して適切なモデルをフィルタリングできます。トップのフィルタリングされた結果は、フランス語のテキストに使用できる感情分析用に調整された多言語の[BERTモデル](https://huggingface.co/nlptown/bert-base-multilingual-uncased-sentiment)を返します:
+
+```py
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+```
+
+
+
+[`AutoModelForSequenceClassification`]と[`AutoTokenizer`]を使用して事前学習済みモデルとそれに関連するトークナイザをロードします(次のセクションで`AutoClass`について詳しく説明します):
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+以下のコードは、[`TFAutoModelForSequenceClassification`]および[`AutoTokenizer`]を使用して、事前学習済みモデルとその関連するトークナイザをロードする方法を示しています(`TFAutoClass`については次のセクションで詳しく説明します):
+
+```python
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+指定したモデルとトークナイザを[`pipeline`]に設定し、今度はフランス語のテキストに`classifier`を適用できます:
+
+```py
+>>> classifier = pipeline("sentiment-analysis", model=model, tokenizer=tokenizer)
+>>> classifier("Nous sommes très heureux de vous présenter la bibliothèque 🤗 Transformers.")
+[{'label': '5 stars', 'score': 0.7273}]
+```
+
+もし、あなたのユースケースに適したモデルが見つからない場合、事前学習済みモデルをあなたのデータでファインチューニングする必要があります。
+ファインチューニングの方法については、[ファインチューニングのチュートリアル](./training)をご覧ください。
+最後に、ファインチューニングした事前学習済みモデルを共有し、コミュニティと共有ハブで共有することを検討してください。これにより、機械学習を民主化する手助けができます! 🤗
+
+## AutoClass
+
+
+
+
+```py
+>>> pt_batch = tokenizer(
+... ["🤗 Transformersライブラリをお見せできて非常に嬉しいです。", "嫌いではないことを願っています。"],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="pt",
+... )
+```
+
+
+
+```py
+>>> tf_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="tf",
+... )
+```
+
+
+
+
+
+[前処理](./preprocessing)チュートリアルをご覧いただき、トークナイゼーションの詳細や、[`AutoImageProcessor`]、[`AutoFeatureExtractor`]、[`AutoProcessor`]を使用して画像、オーディオ、およびマルチモーダル入力を前処理する方法について詳しく説明されているページもご覧ください。
+
+
+
+### AutoModel
+
+
+
+🤗 Transformersは事前学習済みインスタンスを簡単に統一的にロードする方法を提供します。
+これは、[`AutoTokenizer`]をロードするのと同じように[`AutoModel`]をロードできることを意味します。
+タスクに適した[`AutoModel`]を選択する以外の違いはありません。
+テキスト(またはシーケンス)分類の場合、[`AutoModelForSequenceClassification`]をロードする必要があります:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+[`AutoModel`]クラスでサポートされているタスクに関する詳細については、[タスクの概要](./task_summary)を参照してください。
+
+
+
+今、前処理済みのバッチを直接モデルに渡します。辞書を展開するだけで、`**`を追加する必要があります:
+
+```python
+>>> pt_outputs = pt_model(**pt_batch)
+```
+
+モデルは、`logits`属性に最終的なアクティベーションを出力します。 `logits`にsoftmax関数を適用して確率を取得します:
+
+```py
+>>> from torch import nn
+
+>>> pt_predictions = nn.functional.softmax(pt_outputs.logits, dim=-1)
+>>> print(pt_predictions)
+tensor([[0.0021, 0.0018, 0.0115, 0.2121, 0.7725],
+ [0.2084, 0.1826, 0.1969, 0.1755, 0.2365]], grad_fn=)
+```
+
+
+
+🤗 Transformersは事前学習済みインスタンスをロードするためのシンプルで統一された方法を提供します。
+これは、[`TFAutoModel`]を[`AutoTokenizer`]をロードするのと同じようにロードできることを意味します。
+唯一の違いは、タスクに適した[`TFAutoModel`]を選択することです。
+テキスト(またはシーケンス)分類の場合、[`TFAutoModelForSequenceClassification`]をロードする必要があります:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+詳細については、[`AutoModel`]クラスでサポートされているタスクに関する情報は、[タスクの概要](./task_summary)を参照してください。
+
+
+
+次に、前処理済みのバッチを直接モデルに渡します。テンソルをそのまま渡すことができます:
+
+```python
+>>> tf_outputs = tf_model(tf_batch)
+```
+
+モデルは`logits`属性に最終的なアクティベーションを出力します。`logits`にソフトマックス関数を適用して確率を取得します:
+
+```python
+>>> import tensorflow as tf
+
+>>> tf_predictions = tf.nn.softmax(tf_outputs.logits, axis=-1)
+>>> tf_predictions # doctest: +IGNORE_RESULT
+```
+
+
+
+
+
+
+🤗 Transformersのすべてのモデル(PyTorchまたはTensorFlow)は、最終的な活性化関数(softmaxなど)*前*のテンソルを出力します。
+最終的な活性化関数は、しばしば損失と結合されているためです。モデルの出力は特別なデータクラスであり、その属性はIDEで自動補完されます。
+モデルの出力は、タプルまたは辞書のように動作します(整数、スライス、または文字列でインデックスを付けることができます)。
+この場合、Noneである属性は無視されます。
+
+
+
+### Save a Model
+
+
+
+モデルをファインチューニングしたら、[`PreTrainedModel.save_pretrained`]を使用してトークナイザと共に保存できます:
+
+```py
+>>> pt_save_directory = "./pt_save_pretrained"
+>>> tokenizer.save_pretrained(pt_save_directory) # doctest: +IGNORE_RESULT
+>>> pt_model.save_pretrained(pt_save_directory)
+```
+
+再びモデルを使用する準備ができたら、[`PreTrainedModel.from_pretrained`]を使用して再度ロードします:
+
+```py
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("./pt_save_pretrained")
+```
+
+
+
+モデルをファインチューニングしたら、そのトークナイザを使用してモデルを保存できます。[`TFPreTrainedModel.save_pretrained`]を使用します:
+
+```py
+>>> tf_save_directory = "./tf_save_pretrained"
+>>> tokenizer.save_pretrained(tf_save_directory) # doctest: +IGNORE_RESULT
+>>> tf_model.save_pretrained(tf_save_directory)
+```
+
+モデルを再度使用する準備ができたら、[`TFPreTrainedModel.from_pretrained`]を使用して再度ロードします:
+
+```py
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("./tf_save_pretrained")
+```
+
+
+
+
+🤗 Transformersの特に素晴らしい機能の一つは、モデルを保存し、それをPyTorchモデルまたはTensorFlowモデルとして再ロードできることです。 `from_pt`または`from_tf`パラメータを使用してモデルをフレームワーク間で変換できます:
+
+
+
+
+```py
+>>> from transformers import AutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(pt_save_directory)
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(pt_save_directory, from_pt=True)
+```
+
+
+
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(tf_save_directory)
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(tf_save_directory, from_tf=True)
+```
+
+
+
+## Custom model builds
+
+モデルを構築方法を変更するには、モデルの設定クラスを変更できます。設定はモデルの属性を指定します。例えば、隠れ層の数やアテンションヘッドの数などがこれに含まれます。カスタム設定クラスからモデルを初期化する際には、ゼロから始めます。モデルの属性はランダムに初期化され、有意義な結果を得るためにモデルをトレーニングする必要があります。
+
+最初に[`AutoConfig`]をインポートし、変更したい事前学習済みモデルをロードします。[`AutoConfig.from_pretrained`]内で、変更したい属性(例:アテンションヘッドの数)を指定できます:
+
+```python
+>>> from transformers import AutoConfig
+
+>>> my_config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased", n_heads=12)
+```
+
+
+
+[`AutoModel.from_config`]を使用してカスタム設定からモデルを作成します:
+
+```python
+>>> from transformers import AutoModel
+
+>>> my_model = AutoModel.from_config(my_config)
+```
+
+
+
+カスタム構成からモデルを作成するには、[`TFAutoModel.from_config`]を使用します:
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> my_model = TFAutoModel.from_config(my_config)
+```
+
+
+
+
+[カスタムアーキテクチャを作成](./create_a_model)ガイドを参照して、カスタム構成の詳細情報を確認してください。
+
+## Trainer - PyTorch向けの最適化されたトレーニングループ
+
+すべてのモデルは標準の[`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module)であるため、通常のトレーニングループで使用できます。
+独自のトレーニングループを作成できますが、🤗 TransformersはPyTorch向けに[`Trainer`]クラスを提供しており、基本的なトレーニングループに加えて、
+分散トレーニング、混合精度などの機能の追加を行っています。
+
+タスクに応じて、通常は[`Trainer`]に以下のパラメータを渡します:
+
+1. [`PreTrainedModel`]または[`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module)から始めます:
+
+ ```py
+ >>> from transformers import AutoModelForSequenceClassification
+
+ >>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. [`TrainingArguments`]には、変更できるモデルのハイパーパラメータが含まれており、学習率、バッチサイズ、トレーニングエポック数などが変更できます。指定しない場合、デフォルト値が使用されます:
+
+ ```py
+ >>> from transformers import TrainingArguments
+
+ >>> training_args = TrainingArguments(
+ ... output_dir="path/to/save/folder/",
+ ... learning_rate=2e-5,
+ ... per_device_train_batch_size=8,
+ ... per_device_eval_batch_size=8,
+ ... num_train_epochs=2,
+ ... )
+ ```
+
+3. トークナイザ、画像プロセッサ、特徴量抽出器、またはプロセッサのような前処理クラスをロードします:
+
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+4. データセットをロードする:
+
+ ```py
+ >>> from datasets import load_dataset
+
+ >>> dataset = load_dataset("rotten_tomatoes") # doctest: +IGNORE_RESULT
+ ```
+
+5. データセットをトークン化するための関数を作成します:
+
+ ```python
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"])
+ ```
+
+ その後、[`~datasets.Dataset.map`]を使用してデータセット全体に適用します:
+
+ ```python
+ >>> dataset = dataset.map(tokenize_dataset, batched=True)
+ ```
+
+6. データセットからの例のバッチを作成するための [`DataCollatorWithPadding`]:
+
+ ```py
+ >>> from transformers import DataCollatorWithPadding
+
+ >>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+ ```
+
+次に、これらのクラスを[`Trainer`]にまとめます:
+
+```python
+>>> from transformers import Trainer
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=dataset["train"],
+... eval_dataset=dataset["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... ) # doctest: +SKIP
+```
+
+訓練を開始する準備ができたら、[`~Trainer.train`]を呼び出してトレーニングを開始します:
+
+```py
+>>> trainer.train() # doctest: +SKIP
+```
+
+
+
+翻訳や要約など、シーケンス間モデルを使用するタスクには、代わりに[`Seq2SeqTrainer`]と[`Seq2SeqTrainingArguments`]クラスを使用してください。
+
+
+
+[`Trainer`]内のメソッドをサブクラス化することで、トレーニングループの動作をカスタマイズできます。これにより、損失関数、オプティマイザ、スケジューラなどの機能をカスタマイズできます。サブクラス化できるメソッドの一覧については、[`Trainer`]リファレンスをご覧ください。
+
+トレーニングループをカスタマイズする別の方法は、[Callbacks](./main_classes/callback)を使用することです。コールバックを使用して他のライブラリと統合し、トレーニングループを監視して進捗状況を報告したり、トレーニングを早期に停止したりできます。コールバックはトレーニングループ自体には何も変更を加えません。損失関数などのカスタマイズを行う場合は、[`Trainer`]をサブクラス化する必要があります。
+
+## Train with TensorFlow
+
+すべてのモデルは標準の[`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model)であるため、[Keras](https://keras.io/) APIを使用してTensorFlowでトレーニングできます。
+🤗 Transformersは、データセットを`tf.data.Dataset`として簡単にロードできるようにする[`~TFPreTrainedModel.prepare_tf_dataset`]メソッドを提供しており、Kerasの[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)および[`fit`](https://keras.io/api/models/model_training_apis/#fit-method)メソッドを使用してトレーニングをすぐに開始できます。
+
+1. [`TFPreTrainedModel`]または[`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model)から始めます:
+
+ ```py
+ >>> from transformers import TFAutoModelForSequenceClassification
+
+ >>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. トークナイザ、画像プロセッサ、特徴量抽出器、またはプロセッサのような前処理クラスをロードします:
+
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+3. データセットをトークナイズするための関数を作成します:
+
+ ```python
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"]) # doctest: +SKIP
+ ```
+
+4. [`~datasets.Dataset.map`]を使用してデータセット全体にトークナイザを適用し、データセットとトークナイザを[`~TFPreTrainedModel.prepare_tf_dataset`]に渡します。バッチサイズを変更し、データセットをシャッフルすることもできます。
+
+ ```python
+ >>> dataset = dataset.map(tokenize_dataset) # doctest: +SKIP
+ >>> tf_dataset = model.prepare_tf_dataset(
+ ... dataset["train"], batch_size=16, shuffle=True, tokenizer=tokenizer
+ ... ) # doctest: +SKIP
+ ```
+
+5. 準備ができたら、`compile`と`fit`を呼び出してトレーニングを開始できます。 Transformersモデルはすべてデフォルトのタスクに関連する損失関数を持っているため、指定しない限り、損失関数を指定する必要はありません。
+
+ ```python
+ >>> from tensorflow.keras.optimizers import Adam
+
+ >>> model.compile(optimizer=Adam(3e-5)) # 損失関数の引数は不要です!
+ >>> model.fit(tf
+ ```
+
+## What's next?
+
+🤗 Transformersのクイックツアーを完了したら、ガイドをチェックして、カスタムモデルの作成、タスクのためのファインチューニング、スクリプトを使用したモデルのトレーニングなど、より具体的なことを学ぶことができます。🤗 Transformersのコアコンセプトについてもっと詳しく知りたい場合は、コンセプチュアルガイドを読んでみてください!
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/run_scripts.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/run_scripts.md
new file mode 100644
index 0000000000000000000000000000000000000000..af99d1c6da9702a65cdf3c018e2216542cdb5e68
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/run_scripts.md
@@ -0,0 +1,370 @@
+
+
+# Train with a script
+
+🤗 Transformersの[notebooks](./notebooks/README)と一緒に、[PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch)、[TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow)、または[JAX/Flax](https://github.com/huggingface/transformers/tree/main/examples/flax)を使用してモデルをトレーニングする方法を示すサンプルスクリプトもあります。
+
+また、私たちの[研究プロジェクト](https://github.com/huggingface/transformers/tree/main/examples/research_projects)や[レガシーの例](https://github.com/huggingface/transformers/tree/main/examples/legacy)で使用したスクリプトも見つかります。これらのスクリプトは現在メンテナンスされておらず、おそらく最新バージョンのライブラリと互換性がない特定の🤗 Transformersのバージョンが必要です。
+
+サンプルスクリプトはすべての問題でそのまま動作することは期待されておらず、解決しようとしている問題にスクリプトを適応させる必要があるかもしれません。この点をサポートするために、ほとんどのスクリプトはデータがどのように前処理されているかを完全に公開し、必要に応じて編集できるようにしています。
+
+サンプルスクリプトで実装したい機能がある場合は、[フォーラム](https://discuss.huggingface.co/)か[イシュートラッカー](https://github.com/huggingface/transformers/issues)で議論してからプルリクエストを提出してください。バグ修正は歓迎しますが、読みやすさのコストで機能を追加するプルリクエストはほとんどマージされない可能性が高いです。
+
+このガイドでは、[PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization)と[TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/summarization)で実行するサマリゼーショントレーニングスクリプトの実行方法を示します。すべての例は、明示的に指定されていない限り、両方のフレームワークともに動作することが期待されています。
+
+## Setup
+
+最新バージョンのサンプルスクリプトを正常に実行するには、新しい仮想環境に🤗 Transformersをソースからインストールする必要があります:
+
+
+```bash
+git clone https://github.com/huggingface/transformers
+cd transformers
+pip install .
+```
+
+以前のスクリプトのバージョンについては、以下のトグルをクリックしてください:
+
+
+ 以前の🤗 Transformersのバージョンに関する例
+
+
+
+次に、現在の🤗 Transformersのクローンを特定のバージョンに切り替えてください。たとえば、v3.5.1などです。
+
+
+```bash
+git checkout tags/v3.5.1
+```
+
+
+適切なライブラリバージョンを設定したら、任意の例のフォルダに移動し、例固有の要件をインストールします:
+
+
+
+```bash
+pip install -r requirements.txt
+```
+
+## Run a script
+
+
+
+この例のスクリプトは、🤗 [Datasets](https://huggingface.co/docs/datasets/) ライブラリからデータセットをダウンロードし、前処理を行います。次に、[Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) を使用して要約をサポートするアーキテクチャ上でデータセットをファインチューニングします。以下の例では、[CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail) データセット上で [T5-small](https://huggingface.co/google-t5/t5-small) をファインチューニングする方法が示されています。T5 モデルは、そのトレーニング方法に起因して追加の `source_prefix` 引数が必要です。このプロンプトにより、T5 はこれが要約タスクであることを知ることができます。
+
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+
+この例のスクリプトは、🤗 [Datasets](https://huggingface.co/docs/datasets/) ライブラリからデータセットをダウンロードして前処理します。その後、スクリプトは要約をサポートするアーキテクチャ上で Keras を使用してデータセットをファインチューニングします。以下の例では、[T5-small](https://huggingface.co/google-t5/t5-small) を [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail) データセットでファインチューニングする方法を示しています。T5 モデルは、そのトレーニング方法に起因して追加の `source_prefix` 引数が必要です。このプロンプトは、T5 にこれが要約タスクであることを知らせます。
+
+
+```bash
+python examples/tensorflow/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## Distributed training and mixed precision
+
+[Trainer](https://huggingface.co/docs/transformers/main_classes/trainer)は、分散トレーニングと混合精度をサポートしています。つまり、この機能をスクリプトで使用することができます。これらの機能を有効にするには、次の手順を実行します。
+
+- `fp16`引数を追加して混合精度を有効にします。
+- `nproc_per_node`引数で使用するGPUの数を設定します。
+
+以下は提供されたBashコードです。このコードの日本語訳をMarkdown形式で記載します。
+
+```bash
+torchrun \
+ --nproc_per_node 8 pytorch/summarization/run_summarization.py \
+ --fp16 \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+TensorFlowスクリプトは、分散トレーニングに[`MirroredStrategy`](https://www.tensorflow.org/guide/distributed_training#mirroredstrategy)を使用し、トレーニングスクリプトに追加の引数を追加する必要はありません。TensorFlowスクリプトは、デフォルトで複数のGPUが利用可能な場合にそれらを使用します。
+
+## Run a script on a TPU
+
+
+
+Tensor Processing Units (TPUs)は、パフォーマンスを加速させるために特別に設計されています。PyTorchは、[XLA](https://www.tensorflow.org/xla)ディープラーニングコンパイラを使用してTPUsをサポートしており、詳細については[こちら](https://github.com/pytorch/xla/blob/master/README.md)をご覧ください。TPUを使用するには、`xla_spawn.py`スクリプトを起動し、`num_cores`引数を使用して使用するTPUコアの数を設定します。
+```bash
+python xla_spawn.py --num_cores 8 \
+ summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+もちろん、Tensor Processing Units(TPUs)は性能を高速化するために特別に設計されています。TensorFlowスクリプトは、TPUsでトレーニングするために[`TPUStrategy`](https://www.tensorflow.org/guide/distributed_training#tpustrategy)を利用します。TPUを使用するには、TPUリソースの名前を`tpu`引数に渡します。
+
+```bash
+python run_summarization.py \
+ --tpu name_of_tpu_resource \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## Run a script with 🤗 Accelerate
+
+🤗 [Accelerate](https://huggingface.co/docs/accelerate)は、PyTorch専用のライブラリで、CPUのみ、複数のGPU、TPUなど、さまざまなセットアップでモデルをトレーニングするための統一された方法を提供します。PyTorchのトレーニングループを完全に可視化しながら実行できます。まだインストールしていない場合は、🤗 Accelerateをインストールしてください:
+
+> 注意:Accelerateは急速に開発が進行しているため、スクリプトを実行するにはaccelerateのgitバージョンをインストールする必要があります
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+代わりに、`run_summarization_no_trainer.py` スクリプトを使用する必要があります。 🤗 Accelerate がサポートするスクリプトには、フォルダ内に `task_no_trainer.py` ファイルが含まれています。まず、次のコマンドを実行して設定ファイルを作成し、保存します:
+
+```bash
+accelerate config
+```
+
+テストを行い、設定が正しく構成されているか確認してください:
+
+
+```bash
+accelerate test
+```
+
+Now you are ready to launch the training:
+
+
+```bash
+accelerate launch run_summarization_no_trainer.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir ~/tmp/tst-summarization
+```
+
+## Use a custom dataset
+
+要約スクリプトは、CSVまたはJSON Lineファイルであれば、カスタムデータセットをサポートしています。独自のデータセットを使用する場合、いくつかの追加の引数を指定する必要があります。
+
+- `train_file`および`validation_file`は、トレーニングとバリデーションのファイルへのパスを指定します。
+- `text_column`は要約するための入力テキストです。
+- `summary_column`は出力する対象テキストです。
+
+カスタムデータセットを使用した要約スクリプトは、以下のようになります:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --train_file path_to_csv_or_jsonlines_file \
+ --validation_file path_to_csv_or_jsonlines_file \
+ --text_column text_column_name \
+ --summary_column summary_column_name \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --overwrite_output_dir \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --predict_with_generate
+```
+
+## Test a script
+
+すべてが予想通りに動作することを確認するために、データセット全体を処理する前に、データセットの一部の例でスクリプトを実行することは良いアイデアです。以下の引数を使用して、データセットを最大サンプル数に切り詰めます:
+
+- `max_train_samples`
+- `max_eval_samples`
+- `max_predict_samples`
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --max_train_samples 50 \
+ --max_eval_samples 50 \
+ --max_predict_samples 50 \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+一部の例のスクリプトは、`max_predict_samples`引数をサポートしていないことがあります。この引数がサポートされているかどうかがわからない場合は、`-h`引数を追加して確認してください。
+
+```bash
+examples/pytorch/summarization/run_summarization.py -h
+```
+
+## Resume training from checkpoint
+
+以前のチェックポイントからトレーニングを再開するための役立つオプションもあります。これにより、トレーニングが中断された場合でも、最初からやり直すことなく、中断したところから再開できます。チェックポイントからトレーニングを再開するための2つの方法があります。
+
+最初の方法は、`output_dir previous_output_dir` 引数を使用して、`output_dir` に保存された最新のチェックポイントからトレーニングを再開する方法です。この場合、`overwrite_output_dir` を削除する必要があります:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --output_dir previous_output_dir \
+ --predict_with_generate
+```
+
+2番目の方法では、`resume_from_checkpoint path_to_specific_checkpoint` 引数を使用して、特定のチェックポイントフォルダからトレーニングを再開します。
+
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --resume_from_checkpoint path_to_specific_checkpoint \
+ --predict_with_generate
+```
+
+## Share your model
+
+すべてのスクリプトは、最終的なモデルを [Model Hub](https://huggingface.co/models) にアップロードできます。開始する前に Hugging Face にログインしていることを確認してください。
+
+```bash
+huggingface-cli login
+```
+
+次に、スクリプトに `push_to_hub` 引数を追加します。この引数は、Hugging Face のユーザー名と `output_dir` で指定したフォルダ名でリポジトリを作成します。
+
+特定の名前をリポジトリに付けるには、`push_to_hub_model_id` 引数を使用して追加します。このリポジトリは自動的にあなたの名前空間の下にリストされます。
+
+以下の例は、特定のリポジトリ名でモデルをアップロードする方法を示しています:
+
+
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --push_to_hub \
+ --push_to_hub_model_id finetuned-t5-cnn_dailymail \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/serialization.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/serialization.md
new file mode 100644
index 0000000000000000000000000000000000000000..3e9d81180de0464984fa36560c8ba78b7817ec8d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/serialization.md
@@ -0,0 +1,191 @@
+
+
+# Export to ONNX
+
+🤗 Transformersモデルを本番環境に展開する際には、モデルを特殊なランタイムおよびハードウェアで読み込み、実行できるように、モデルをシリアライズされた形式にエクスポートすることが必要であるか、その恩恵を受けることができることがあります。
+
+🤗 Optimumは、Transformersの拡張機能であり、PyTorchまたはTensorFlowからモデルをONNXやTFLiteなどのシリアライズされた形式にエクスポートすることを可能にする「exporters」モジュールを提供しています。また、🤗 Optimumは、最大の効率でターゲットハードウェアでモデルをトレーニングおよび実行するためのパフォーマンス最適化ツールも提供しています。
+
+このガイドでは、🤗 Transformersモデルを🤗 Optimumを使用してONNXにエクスポートする方法を示しており、モデルをTFLiteにエクスポートする方法については[Export to TFLiteページ](tflite)を参照してください。
+
+## Export to ONNX
+
+[ONNX(Open Neural Network eXchange)](http://onnx.ai)は、PyTorchおよびTensorFlowを含むさまざまなフレームワークで深層学習モデルを表現するための共通の一連の演算子とファイル形式を定義するオープンスタンダードです。モデルがONNX形式にエクスポートされると、これらの演算子はニューラルネットワークを介するデータの流れを表す計算グラフ(一般的には「中間表現」と呼ばれる)を構築するために使用されます。
+
+標準化された演算子とデータ型を備えたグラフを公開することで、ONNXはフレームワーク間の切り替えを容易にします。たとえば、PyTorchでトレーニングされたモデルはONNX形式にエクスポートし、それをTensorFlowでインポートすることができます(逆も同様です)。
+
+ONNX形式にエクスポートされたモデルは、以下のように使用できます:
+- [グラフ最適化](https://huggingface.co/docs/optimum/onnxruntime/usage_guides/optimization)や[量子化](https://huggingface.co/docs/optimum/onnxruntime/usage_guides/quantization)などのテクニックを使用して推論のために最適化。
+- [`ORTModelForXXX`クラス](https://huggingface.co/docs/optimum/onnxruntime/package_reference/modeling_ort)を介してONNX Runtimeで実行し、🤗 Transformersでおなじみの`AutoModel` APIに従います。
+- [最適化された推論パイプライン](https://huggingface.co/docs/optimum/main/en/onnxruntime/usage_guides/pipelines)を介して実行し、🤗 Transformersの[`pipeline`]関数と同じAPIを持っています。
+
+🤗 Optimumは、設定オブジェクトを活用してONNXエクスポートをサポートしており、これらの設定オブジェクトは多くのモデルアーキテクチャ用に事前に作成されており、他のアーキテクチャにも簡単に拡張できるように設計されています。
+
+事前に作成された設定のリストについては、[🤗 Optimumドキュメント](https://huggingface.co/docs/optimum/exporters/onnx/overview)を参照してください。
+
+🤗 TransformersモデルをONNXにエクスポートする方法は2つあります。以下では両方の方法を示します:
+
+- export with 🤗 Optimum via CLI.
+- export with 🤗 Optimum with `optimum.onnxruntime`.
+
+### Exporting a 🤗 Transformers model to ONNX with CLI
+
+🤗 TransformersモデルをONNXにエクスポートするには、まず追加の依存関係をインストールしてください:
+
+```bash
+pip install optimum[exporters]
+```
+
+すべての利用可能な引数を確認するには、[🤗 Optimumドキュメント](https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/export_a_model#exporting-a-model-to-onnx-using-the-cli)を参照してください。または、コマンドラインでヘルプを表示することもできます:
+
+
+```bash
+optimum-cli export onnx --help
+```
+
+🤗 Hubからモデルのチェックポイントをエクスポートするには、例えば `distilbert/distilbert-base-uncased-distilled-squad` を使いたい場合、以下のコマンドを実行してください:
+
+```bash
+optimum-cli export onnx --model distilbert/distilbert-base-uncased-distilled-squad distilbert_base_uncased_squad_onnx/
+```
+
+進行状況を示し、結果の `model.onnx` が保存される場所を表示するログは、以下のように表示されるはずです:
+
+
+```bash
+Validating ONNX model distilbert_base_uncased_squad_onnx/model.onnx...
+ -[✓] ONNX model output names match reference model (start_logits, end_logits)
+ - Validating ONNX Model output "start_logits":
+ -[✓] (2, 16) matches (2, 16)
+ -[✓] all values close (atol: 0.0001)
+ - Validating ONNX Model output "end_logits":
+ -[✓] (2, 16) matches (2, 16)
+ -[✓] all values close (atol: 0.0001)
+The ONNX export succeeded and the exported model was saved at: distilbert_base_uncased_squad_onnx
+```
+
+上記の例は🤗 Hubからのチェックポイントのエクスポートを示しています。ローカルモデルをエクスポートする場合、まずモデルの重みとトークナイザのファイルを同じディレクトリ(`local_path`)に保存してください。CLIを使用する場合、🤗 Hubのチェックポイント名の代わりに`model`引数に`local_path`を渡し、`--task`引数を指定してください。[🤗 Optimumドキュメント](https://huggingface.co/docs/optimum/exporters/task_manager)でサポートされているタスクのリストを確認できます。`task`引数が指定されていない場合、タスク固有のヘッドを持たないモデルアーキテクチャがデフォルトで選択されます。
+
+
+```bash
+optimum-cli export onnx --model local_path --task question-answering distilbert_base_uncased_squad_onnx/
+```
+
+エクスポートされた `model.onnx` ファイルは、ONNX標準をサポートする[多くのアクセラレータ](https://onnx.ai/supported-tools.html#deployModel)の1つで実行できます。たとえば、[ONNX Runtime](https://onnxruntime.ai/)を使用してモデルを読み込み、実行する方法は以下の通りです:
+
+
+```python
+>>> from transformers import AutoTokenizer
+>>> from optimum.onnxruntime import ORTModelForQuestionAnswering
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert_base_uncased_squad_onnx")
+>>> model = ORTModelForQuestionAnswering.from_pretrained("distilbert_base_uncased_squad_onnx")
+>>> inputs = tokenizer("What am I using?", "Using DistilBERT with ONNX Runtime!", return_tensors="pt")
+>>> outputs = model(**inputs)
+```
+
+🤗 HubからTensorFlowのチェックポイントをエクスポートするプロセスは、同様です。例えば、[Keras organization](https://huggingface.co/keras-io)から純粋なTensorFlowのチェックポイントをエクスポートする方法は以下の通りです:
+
+
+```bash
+optimum-cli export onnx --model keras-io/transformers-qa distilbert_base_cased_squad_onnx/
+```
+
+### Exporting a 🤗 Transformers model to ONNX with `optimum.onnxruntime`
+
+CLIの代わりに、🤗 TransformersモデルをONNXにプログラム的にエクスポートすることもできます。以下のように行います:
+
+```python
+>>> from optimum.onnxruntime import ORTModelForSequenceClassification
+>>> from transformers import AutoTokenizer
+
+>>> model_checkpoint = "distilbert_base_uncased_squad"
+>>> save_directory = "onnx/"
+
+>>> # Load a model from transformers and export it to ONNX
+>>> ort_model = ORTModelForSequenceClassification.from_pretrained(model_checkpoint, export=True)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_checkpoint)
+
+>>> # Save the onnx model and tokenizer
+>>> ort_model.save_pretrained(save_directory)
+>>> tokenizer.save_pretrained(save_directory)
+```
+
+### Exporting a model for an unsupported architecture
+
+現在エクスポートできないモデルをサポートするために貢献したい場合、まず[`optimum.exporters.onnx`](https://huggingface.co/docs/optimum/exporters/onnx/overview)でサポートされているかどうかを確認し、サポートされていない場合は[🤗 Optimumに貢献](https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/contribute)してください。
+
+### Exporting a model with `transformers.onnx`
+
+
+
+`transformers.onnx`はもはやメンテナンスされていないため、モデルを上記で説明したように🤗 Optimumでエクスポートしてください。このセクションは将来のバージョンで削除されます。
+
+
+
+🤗 TransformersモデルをONNXにエクスポートするには、追加の依存関係をインストールしてください:
+
+
+```bash
+pip install transformers[onnx]
+```
+
+`transformers.onnx`パッケージをPythonモジュールとして使用して、事前に用意された設定を使用してチェックポイントをエクスポートする方法は以下の通りです:
+
+```bash
+python -m transformers.onnx --model=distilbert/distilbert-base-uncased onnx/
+```
+
+この方法は、`--model`引数で定義されたチェックポイントのONNXグラフをエクスポートします。🤗 Hubのいずれかのチェックポイントまたはローカルに保存されたチェックポイントを渡すことができます。エクスポートされた`model.onnx`ファイルは、ONNX標準をサポートする多くのアクセラレータで実行できます。例えば、ONNX Runtimeを使用してモデルを読み込んで実行する方法は以下の通りです:
+
+
+```python
+>>> from transformers import AutoTokenizer
+>>> from onnxruntime import InferenceSession
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> session = InferenceSession("onnx/model.onnx")
+>>> # ONNX Runtime expects NumPy arrays as input
+>>> inputs = tokenizer("Using DistilBERT with ONNX Runtime!", return_tensors="np")
+>>> outputs = session.run(output_names=["last_hidden_state"], input_feed=dict(inputs))
+```
+
+必要な出力名(例: `["last_hidden_state"]`)は、各モデルのONNX構成を確認することで取得できます。例えば、DistilBERTの場合、次のようになります:
+
+
+```python
+>>> from transformers.models.distilbert import DistilBertConfig, DistilBertOnnxConfig
+
+>>> config = DistilBertConfig()
+>>> onnx_config = DistilBertOnnxConfig(config)
+>>> print(list(onnx_config.outputs.keys()))
+["last_hidden_state"]
+```
+
+ハブから純粋なTensorFlowのチェックポイントをプログラム的にエクスポートするプロセスは、以下のように同様です:
+
+```bash
+python -m transformers.onnx --model=keras-io/transformers-qa onnx/
+```
+
+ローカルに保存されたモデルをエクスポートする場合、モデルの重みとトークナイザのファイルを同じディレクトリに保存してください(例: `local-pt-checkpoint`)。その後、`transformers.onnx`パッケージの `--model`引数を希望するディレクトリに向けて設定して、ONNXにエクスポートします:
+
+
+```bash
+python -m transformers.onnx --model=local-pt-checkpoint onnx/
+```
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/task_summary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/task_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..93f4783b1520103fd50243eeb4347605b8fba9d8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/task_summary.md
@@ -0,0 +1,355 @@
+
+
+# What 🤗 Transformers can do
+
+🤗 Transformersは、自然言語処理(NLP)、コンピュータビジョン、音声処理などの最新の事前学習済みモデルのライブラリです。このライブラリには、Transformerモデルだけでなく、コンピュータビジョンタスク向けのモダンな畳み込みニューラルネットワークなど、Transformer以外のモデルも含まれています。現代のスマートフォン、アプリ、テレビなど、最も人気のある消費者製品の多くには、深層学習技術が使用されています。スマートフォンで撮影した写真から背景オブジェクトを削除したいですか?これはパノプティック・セグメンテーション(まだ何を意味するかわからなくても心配しないでください、以下のセクションで説明します!)のタスクの一例です。
+
+このページでは、🤗 Transformersライブラリを使用して、たった3行のコードで解決できるさまざまな音声および音声、コンピュータビジョン、NLPタスクの概要を提供します!
+
+## Audio
+
+音声と音声処理のタスクは、他のモダリティとは少し異なります。なぜなら、入力としての生の音声波形は連続的な信号であるからです。テキストとは異なり、生の音声波形は文章を単語に分割できるようにきれいに分割できません。これを解決するために、通常、生の音声信号は定期的な間隔でサンプリングされます。間隔内でより多くのサンプルを取ると、サンプリングレートが高くなり、音声はより元の音声ソースに近づきます。
+
+以前のアプローチでは、音声を前処理してそれから有用な特徴を抽出しました。しかし、現在では、生の音声波形を特徴エンコーダに直接フィードし、音声表現を抽出することから始めることが一般的です。これにより、前処理ステップが簡素化され、モデルは最も重要な特徴を学習できます。
+
+### Audio classification
+
+音声分類は、事前に定義されたクラスのセットから音声データにラベルを付けるタスクです。これは多くの具体的なアプリケーションを含む広範なカテゴリであり、いくつかの例は次のとおりです:
+
+- 音響シーン分類:音声にシーンラベルを付ける(「オフィス」、「ビーチ」、「スタジアム」)
+- 音響イベント検出:音声に音声イベントラベルを付ける(「車のクラクション」、「クジラの呼び声」、「ガラスの破裂」)
+- タギング:複数の音を含む音声にラベルを付ける(鳥の鳴き声、会議でのスピーカー識別)
+- 音楽分類:音楽にジャンルラベルを付ける(「メタル」、「ヒップホップ」、「カントリー」)
+
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="audio-classification", model="superb/hubert-base-superb-er")
+>>> preds = classifier("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4532, 'label': 'hap'},
+ {'score': 0.3622, 'label': 'sad'},
+ {'score': 0.0943, 'label': 'neu'},
+ {'score': 0.0903, 'label': 'ang'}]
+```
+
+### Automatic speech recognition
+
+自動音声認識(ASR)は音声をテキストに変換します。これは、人間のコミュニケーションの自然な形式である音声の一部として、部分的にそのような一般的なオーディオタスクの一つです。今日、ASRシステムはスピーカー、スマートフォン、自動車などの「スマート」テクノロジープロダクトに組み込まれています。私たちは仮想アシスタントに音楽を再生してもらったり、リマインダーを設定してもらったり、天気を教えてもらったりできます。
+
+しかし、Transformerアーキテクチャが助けた主要な課題の一つは、低リソース言語におけるものです。大量の音声データで事前トレーニングし、低リソース言語でラベル付き音声データをわずか1時間だけでファインチューニングすることでも、以前のASRシステムと比較して高品質な結果を得ることができます。以前のASRシステムは100倍以上のラベル付きデータでトレーニングされていましたが、Transformerアーキテクチャはこの問題に貢献しました。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline(task="automatic-speech-recognition", model="openai/whisper-small")
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+
+## Computer vision
+
+最初で初めて成功したコンピュータビジョンのタスクの一つは、[畳み込みニューラルネットワーク(CNN)](glossary#convolution)を使用して郵便番号の画像を認識することでした。画像はピクセルから構成され、各ピクセルには数値があります。これにより、画像をピクセル値の行列として簡単に表現できます。特定のピクセル値の組み合わせは、画像の色を記述します。
+
+コンピュータビジョンのタスクを解決する一般的な方法は次の2つです:
+
+1. 畳み込みを使用して、低レベルの特徴から高レベルの抽象的な情報まで、画像の階層的な特徴を学習する。
+2. 画像をパッチに分割し、各画像パッチが画像全体とどのように関連しているかを徐々に学習するためにTransformerを使用する。CNNが好むボトムアップアプローチとは異なり、これはぼんやりとした画像から始めて徐々に焦点を合わせるようなものです。
+
+### Image classification
+
+画像分類は、事前に定義されたクラスのセットから画像全体にラベルを付けます。多くの分類タスクと同様に、画像分類には多くの実用的な用途があり、その一部は次のとおりです:
+
+* 医療:疾患の検出や患者の健康の監視に使用するために医療画像にラベルを付ける
+* 環境:森林伐採の監視、野生地の管理情報、または山火事の検出に使用するために衛星画像にラベルを付ける
+* 農業:作物の健康を監視するための作物の画像や、土地利用の監視のための衛星画像にラベルを付ける
+* 生態学:野生動物の個体数を監視したり、絶滅危惧種を追跡するために動植物の種の画像にラベルを付ける
+
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="image-classification")
+>>> preds = classifier(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> print(*preds, sep="\n")
+{'score': 0.4335, 'label': 'lynx, catamount'}
+{'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}
+{'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}
+{'score': 0.0239, 'label': 'Egyptian cat'}
+{'score': 0.0229, 'label': 'tiger cat'}
+```
+
+### Object detection
+
+画像分類とは異なり、オブジェクト検出は画像内の複数のオブジェクトを識別し、オブジェクトの位置を画像内で定義する境界ボックスによって特定します。オブジェクト検出の例には次のような用途があります:
+
+* 自動運転車:他の車両、歩行者、信号機などの日常の交通オブジェクトを検出
+* リモートセンシング:災害モニタリング、都市計画、天候予測
+* 欠陥検出:建物のクラックや構造上の損傷、製造上の欠陥を検出
+
+
+```py
+>>> from transformers import pipeline
+
+>>> detector = pipeline(task="object-detection")
+>>> preds = detector(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"], "box": pred["box"]} for pred in preds]
+>>> preds
+[{'score': 0.9865,
+ 'label': 'cat',
+ 'box': {'xmin': 178, 'ymin': 154, 'xmax': 882, 'ymax': 598}}]
+```
+
+### Image segmentation
+
+画像セグメンテーションは、画像内のすべてのピクセルをクラスに割り当てるピクセルレベルのタスクです。これはオブジェクト検出とは異なり、オブジェクトをラベル付けし、予測するために境界ボックスを使用する代わりに、セグメンテーションはより詳細になります。セグメンテーションはピクセルレベルでオブジェクトを検出できます。画像セグメンテーションにはいくつかのタイプがあります:
+
+* インスタンスセグメンテーション:オブジェクトのクラスをラベル付けするだけでなく、オブジェクトの個別のインスタンス("犬-1"、"犬-2")もラベル付けします。
+* パノプティックセグメンテーション:セマンティックセグメンテーションとインスタンスセグメンテーションの組み合わせ。セマンティッククラスごとに各ピクセルにラベルを付け、オブジェクトの個別のインスタンスもラベル付けします。
+
+セグメンテーションタスクは、自動運転車にとって、周囲の世界のピクセルレベルのマップを作成し、歩行者や他の車両を安全に回避できるようにするのに役立ちます。また、医療画像では、タスクの細かい粒度が異常な細胞や臓器の特徴を識別するのに役立ちます。画像セグメンテーションは、eコマースで衣類を仮想的に試着したり、カメラを通じて実世界にオブジェクトを重ねて拡張現実の体験を作成したりするためにも使用できます。
+
+
+
+```py
+>>> from transformers import pipeline
+
+>>> segmenter = pipeline(task="image-segmentation")
+>>> preds = segmenter(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> print(*preds, sep="\n")
+{'score': 0.9879, 'label': 'LABEL_184'}
+{'score': 0.9973, 'label': 'snow'}
+{'score': 0.9972, 'label': 'cat'}
+```
+
+### Depth estimation
+
+深度推定は、画像内の各ピクセルがカメラからの距離を予測します。このコンピュータビジョンタスクは、特にシーンの理解と再構築に重要です。たとえば、自動運転車では、歩行者、交通標識、他の車などの物体がどれだけ遠いかを理解し、障害物や衝突を回避するために必要です。深度情報はまた、2D画像から3D表現を構築し、生物学的構造や建物の高品質な3D表現を作成するのに役立ちます。
+
+深度推定には次の2つのアプローチがあります:
+
+* ステレオ:深度は、わずかに異なる角度からの同じ画像の2つの画像を比較して推定されます。
+* モノキュラー:深度は単一の画像から推定されます。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> depth_estimator = pipeline(task="depth-estimation")
+>>> preds = depth_estimator(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+```
+
+
+## Natural language processing
+
+NLPタスクは、テキストが私たちにとって自然なコミュニケーション手段であるため、最も一般的なタスクの一つです。モデルが認識するための形式にテキストを変換するには、トークン化が必要です。これは、テキストのシーケンスを単語やサブワード(トークン)に分割し、それらのトークンを数字に変換することを意味します。その結果、テキストのシーケンスを数字のシーケンスとして表現し、一度数字のシーケンスがあれば、さまざまなNLPタスクを解決するためにモデルに入力できます!
+
+### Text classification
+
+どんなモダリティの分類タスクと同様に、テキスト分類は事前に定義されたクラスのセットからテキストのシーケンス(文レベル、段落、またはドキュメントであることがあります)にラベルを付けます。テキスト分類には多くの実用的な用途があり、その一部は次のとおりです:
+
+* 感情分析:`positive`や`negative`のような極性に従ってテキストにラベルを付け、政治、金融、マーケティングなどの分野での意思決定をサポートします。
+* コンテンツ分類:テキストをトピックに従ってラベル付けし、ニュースやソーシャルメディアのフィード内の情報を整理し、フィルタリングするのに役立ちます(`天気`、`スポーツ`、`金融`など)。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="sentiment-analysis")
+>>> preds = classifier("Hugging Face is the best thing since sliced bread!")
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.9991, 'label': 'POSITIVE'}]
+```
+
+### Token classification
+
+どんなNLPタスクでも、テキストはテキストのシーケンスを個々の単語やサブワードに分割して前処理されます。これらは[トークン](/glossary#token)として知られています。トークン分類は、事前に定義されたクラスのセットから各トークンにラベルを割り当てます。
+
+トークン分類の一般的なタイプは次の2つです:
+
+* 固有表現認識(NER):組織、人物、場所、日付などのエンティティのカテゴリに従ってトークンにラベルを付けます。NERは特にバイオメディカル環境で人気であり、遺伝子、タンパク質、薬物名などをラベル付けできます。
+* 品詞タグ付け(POS):名詞、動詞、形容詞などの品詞に従ってトークンにラベルを付けます。POSは、翻訳システムが同じ単語が文法的にどのように異なるかを理解するのに役立ちます(名詞としての「銀行」と動詞としての「銀行」など)。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="ner")
+>>> preds = classifier("Hugging Face is a French company based in New York City.")
+>>> preds = [
+... {
+... "entity": pred["entity"],
+... "score": round(pred["score"], 4),
+... "index": pred["index"],
+... "word": pred["word"],
+... "start": pred["start"],
+... "end": pred["end"],
+... }
+... for pred in preds
+... ]
+>>> print(*preds, sep="\n")
+{'entity': 'I-ORG', 'score': 0.9968, 'index': 1, 'word': 'Hu', 'start': 0, 'end': 2}
+{'entity': 'I-ORG', 'score': 0.9293, 'index': 2, 'word': '##gging', 'start': 2, 'end': 7}
+{'entity': 'I-ORG', 'score': 0.9763, 'index': 3, 'word': 'Face', 'start': 8, 'end': 12}
+{'entity': 'I-MISC', 'score': 0.9983, 'index': 6, 'word': 'French', 'start': 18, 'end': 24}
+{'entity': 'I-LOC', 'score': 0.999, 'index': 10, 'word': 'New', 'start': 42, 'end': 45}
+{'entity': 'I-LOC', 'score': 0.9987, 'index': 11, 'word': 'York', 'start': 46, 'end': 50}
+{'entity': 'I-LOC', 'score': 0.9992, 'index': 12, 'word': 'City', 'start': 51, 'end': 55}
+```
+
+### Question answering
+
+質問応答は、コンテキスト(オープンドメイン)を含む場合と含まない場合(クローズドドメイン)がある場合もある、別のトークンレベルのタスクで、質問に対する回答を返します。このタスクは、仮想アシスタントにレストランが営業しているかどうかのような質問をするときに発生します。また、顧客や技術サポートを提供し、検索エンジンがあなたが求めている関連情報を取得するのにも役立ちます。
+
+質問応答の一般的なタイプは次の2つです:
+
+* 抽出型:質問と一部のコンテキストが与えられた場合、モデルがコンテキストから抽出する必要のあるテキストのスパンが回答となります。
+* 抽象的:質問と一部のコンテキストが与えられた場合、回答はコンテキストから生成されます。このアプローチは、[`QuestionAnsweringPipeline`]ではなく[`Text2TextGenerationPipeline`]で処理されます。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> question_answerer = pipeline(task="question-answering")
+>>> preds = question_answerer(
+... question="What is the name of the repository?",
+... context="The name of the repository is huggingface/transformers",
+... )
+>>> print(
+... f"score: {round(preds['score'], 4)}, start: {preds['start']}, end: {preds['end']}, answer: {preds['answer']}"
+... )
+score: 0.9327, start: 30, end: 54, answer: huggingface/transformers
+```
+
+### Summarization
+
+要約は、長いテキストから短いバージョンを作成し、元の文書の意味の大部分を保ちながら試みるタスクです。要約はシーケンスからシーケンスへのタスクであり、入力よりも短いテキストシーケンスを出力します。要約を行うことで、読者が主要なポイントを迅速に理解できるようにするのに役立つ長文書がたくさんあります。法案、法的および財務文書、特許、科学論文など、読者の時間を節約し読書の支援となる文書の例があります。
+
+質問応答と同様に、要約には2つのタイプがあります:
+
+* 抽出的要約:元のテキストから最も重要な文を識別して抽出します。
+* 抽象的要約:元のテキストからターゲットの要約(入力文書に含まれていない新しい単語を含むことがあります)を生成します。[`SummarizationPipeline`]は抽象的なアプローチを使用しています。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> summarizer = pipeline(task="summarization")
+>>> summarizer(
+... "In this work, we presented the Transformer, the first sequence transduction model based entirely on attention, replacing the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention. For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers. On both WMT 2014 English-to-German and WMT 2014 English-to-French translation tasks, we achieve a new state of the art. In the former task our best model outperforms even all previously reported ensembles."
+... )
+[{'summary_text': ' The Transformer is the first sequence transduction model based entirely on attention . It replaces the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention . For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers .'}]
+```
+
+### Translation
+
+翻訳は、ある言語のテキストシーケンスを別の言語に変換する作業です。これは異なるバックグラウンドを持つ人々がコミュニケーションをとるのに役立ち、広範な観客にコンテンツを翻訳して伝えるのに役立ち、新しい言語を学ぶのを支援する学習ツールにもなります。要約と共に、翻訳はシーケンス間のタスクであり、モデルは入力シーケンスを受け取り、ターゲットの出力シーケンスを返します。
+
+初期の翻訳モデルは主に単一言語でしたが、最近では多言語モデルに対する関心が高まり、多くの言語対で翻訳できるような多言語モデルに注目が集まっています。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> text = "translate English to French: Hugging Face is a community-based open-source platform for machine learning."
+>>> translator = pipeline(task="translation", model="google-t5/t5-small")
+>>> translator(text)
+[{'translation_text': "Hugging Face est une tribune communautaire de l'apprentissage des machines."}]
+```
+
+### 言語モデリング
+
+言語モデリングは、テキストのシーケンス内の単語を予測するタスクです。事前学習された言語モデルは、多くの他のダウンストリームタスクに対してファインチューニングできるため、非常に人気のあるNLPタスクとなっています。最近では、ゼロショットまたはフューショット学習を実証する大規模な言語モデル(LLM)に大きな関心が寄せられています。これは、モデルが明示的にトレーニングされていないタスクを解決できることを意味します!言語モデルは、流暢で説得力のあるテキストを生成するために使用できますが、テキストが常に正確であるわけではないため、注意が必要です。
+
+言語モデリングには2つのタイプがあります:
+
+* 因果的:モデルの目標は、シーケンス内の次のトークンを予測することであり、将来のトークンはマスクされます。
+
+ ```py
+ >>> from transformers import pipeline
+
+ >>> prompt = "Hugging Face is a community-based open-source platform for machine learning."
+ >>> generator = pipeline(task="text-generation")
+ >>> generator(prompt) # doctest: +SKIP
+ ```
+
+* マスクされた:モデルの目的は、シーケンス内のトークン全体にアクセスしながら、シーケンス内のマスクされたトークンを予測することです。
+
+ ```py
+ >>> text = "Hugging Face is a community-based open-source for machine learning."
+ >>> fill_mask = pipeline(task="fill-mask")
+ >>> preds = fill_mask(text, top_k=1)
+ >>> preds = [
+ ... {
+ ... "score": round(pred["score"], 4),
+ ... "token": pred["token"],
+ ... "token_str": pred["token_str"],
+ ... "sequence": pred["sequence"],
+ ... }
+ ... for pred in preds
+ ... ]
+ >>> preds
+ [{'score': 0.2236,
+ 'token': 1761,
+ 'token_str': ' platform',
+ 'sequence': 'Hugging Face is a community-based open-source platform for machine learning.'}]
+ ```
+
+## Multimodal
+
+マルチモーダルタスクは、特定の問題を解決するために複数のデータモダリティ(テキスト、画像、音声、ビデオ)を処理するためにモデルを必要とします。画像キャプショニングは、モデルが入力として画像を受け取り、画像を説明するテキストのシーケンスまたは画像のいくつかの特性を出力するマルチモーダルタスクの例です。
+
+マルチモーダルモデルは異なるデータタイプまたはモダリティで作業しますが、内部的には前処理ステップがモデルにすべてのデータタイプを埋め込み(データに関する意味のある情報を保持するベクトルまたは数字のリスト)に変換するのを支援します。画像キャプショニングのようなタスクでは、モデルは画像の埋め込みとテキストの埋め込みの間の関係を学習します。
+
+### Document question answering
+
+ドキュメント質問応答は、ドキュメントからの自然言語の質問に答えるタスクです。テキストを入力とするトークンレベルの質問応答タスクとは異なり、ドキュメント質問応答はドキュメントの画像とそのドキュメントに関する質問を受け取り、答えを返します。ドキュメント質問応答は構造化されたドキュメントを解析し、それから重要な情報を抽出するために使用できます。以下の例では、レシートから合計金額とお釣りを抽出することができます。
+
+
+```py
+>>> from transformers import pipeline
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "https://huggingface.co/datasets/hf-internal-testing/example-documents/resolve/main/jpeg_images/2.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> doc_question_answerer = pipeline("document-question-answering", model="magorshunov/layoutlm-invoices")
+>>> preds = doc_question_answerer(
+... question="What is the total amount?",
+... image=image,
+... )
+>>> preds
+[{'score': 0.8531, 'answer': '17,000', 'start': 4, 'end': 4}]
+```
+
+このページが各モダリティのタスクの種類とそれぞれの重要性についての追加の背景情報を提供できたことを願っています。次の [セクション](tasks_explained) では、🤗 トランスフォーマーがこれらのタスクを解決するために **どのように** 動作するかを学びます。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/asr.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/asr.md
new file mode 100644
index 0000000000000000000000000000000000000000..ebefeba831a03e823ae57fd4f0c3f3aa127d5c64
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/asr.md
@@ -0,0 +1,375 @@
+
+
+# Automatic speech recognition
+
+[[open-in-colab]]
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/automatic-speech-recognition) を確認することをお勧めします。
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install transformers datasets evaluate jiwer
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load MInDS-14 dataset
+
+まず、🤗 データセット ライブラリから [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) データセットの小さいサブセットをロードします。これにより、完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> minds = load_dataset("PolyAI/minds14", name="en-US", split="train[:100]")
+```
+
+[`~Dataset.train_test_split`] メソッドを使用して、データセットの `train` 分割をトレイン セットとテスト セットに分割します。
+
+```py
+>>> minds = minds.train_test_split(test_size=0.2)
+```
+
+次に、データセットを見てみましょう。
+
+```py
+>>> minds
+DatasetDict({
+ train: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 16
+ })
+ test: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 4
+ })
+})
+```
+
+データセットには`lang_id`や`english_transcription`などの多くの有用な情報が含まれていますが、このガイドでは「`audio`」と「`transciption`」に焦点を当てます。 [`~datasets.Dataset.remove_columns`] メソッドを使用して他の列を削除します。
+
+```py
+>>> minds = minds.remove_columns(["english_transcription", "intent_class", "lang_id"])
+```
+
+もう一度例を見てみましょう。
+
+```py
+>>> minds["train"][0]
+{'audio': {'array': array([-0.00024414, 0. , 0. , ..., 0.00024414,
+ 0.00024414, 0.00024414], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'sampling_rate': 8000},
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
+```
+
+次の 2 つのフィールドがあります。
+
+- `audio`: 音声ファイルをロードしてリサンプリングするために呼び出す必要がある音声信号の 1 次元の `array`。
+- `transcription`: ターゲットテキスト。
+
+## Preprocess
+
+次のステップでは、Wav2Vec2 プロセッサをロードしてオーディオ信号を処理します。
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base")
+```
+
+MInDS-14 データセットのサンプリング レートは 8000kHz です (この情報は [データセット カード](https://huggingface.co/datasets/PolyAI/minds14) で確認できます)。つまり、データセットを再サンプリングする必要があります。事前トレーニングされた Wav2Vec2 モデルを使用するには、16000kHz に設定します。
+
+```py
+>>> minds = minds.cast_column("audio", Audio(sampling_rate=16_000))
+>>> minds["train"][0]
+{'audio': {'array': array([-2.38064706e-04, -1.58618059e-04, -5.43987835e-06, ...,
+ 2.78103951e-04, 2.38446111e-04, 1.18740834e-04], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'sampling_rate': 16000},
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
+```
+
+上の `transcription` でわかるように、テキストには大文字と小文字が混在しています。 Wav2Vec2 トークナイザーは大文字のみでトレーニングされるため、テキストがトークナイザーの語彙と一致することを確認する必要があります。
+
+```py
+>>> def uppercase(example):
+... return {"transcription": example["transcription"].upper()}
+
+
+>>> minds = minds.map(uppercase)
+```
+
+次に、次の前処理関数を作成します。
+
+1. `audio`列を呼び出して、オーディオ ファイルをロードしてリサンプリングします。
+2. オーディオ ファイルから `input_values` を抽出し、プロセッサを使用して `transcription` 列をトークン化します。
+
+```py
+>>> def prepare_dataset(batch):
+... audio = batch["audio"]
+... batch = processor(audio["array"], sampling_rate=audio["sampling_rate"], text=batch["transcription"])
+... batch["input_length"] = len(batch["input_values"][0])
+... return batch
+```
+
+データセット全体に前処理関数を適用するには、🤗 Datasets [`~datasets.Dataset.map`] 関数を使用します。 `num_proc` パラメータを使用してプロセスの数を増やすことで、`map` を高速化できます。 [`~datasets.Dataset.remove_columns`] メソッドを使用して、不要な列を削除します。
+
+```py
+>>> encoded_minds = minds.map(prepare_dataset, remove_columns=minds.column_names["train"], num_proc=4)
+```
+
+🤗 Transformers には ASR 用のデータ照合器がないため、[`DataCollatorWithPadding`] を調整してサンプルのバッチを作成する必要があります。また、テキストとラベルが (データセット全体ではなく) バッチ内の最も長い要素の長さに合わせて動的に埋め込まれ、均一な長さになります。 `padding=True` を設定すると、`tokenizer` 関数でテキストを埋め込むことができますが、動的な埋め込みの方が効率的です。
+
+他のデータ照合器とは異なり、この特定のデータ照合器は、`input_values`と `labels`」に異なるパディング方法を適用する必要があります。
+
+```py
+>>> import torch
+
+>>> from dataclasses import dataclass, field
+>>> from typing import Any, Dict, List, Optional, Union
+
+
+>>> @dataclass
+... class DataCollatorCTCWithPadding:
+... processor: AutoProcessor
+... padding: Union[bool, str] = "longest"
+
+... def __call__(self, features: List[Dict[str, Union[List[int], torch.Tensor]]]) -> Dict[str, torch.Tensor]:
+... # split inputs and labels since they have to be of different lengths and need
+... # different padding methods
+... input_features = [{"input_values": feature["input_values"][0]} for feature in features]
+... label_features = [{"input_ids": feature["labels"]} for feature in features]
+
+... batch = self.processor.pad(input_features, padding=self.padding, return_tensors="pt")
+
+... labels_batch = self.processor.pad(labels=label_features, padding=self.padding, return_tensors="pt")
+
+... # replace padding with -100 to ignore loss correctly
+... labels = labels_batch["input_ids"].masked_fill(labels_batch.attention_mask.ne(1), -100)
+
+... batch["labels"] = labels
+
+... return batch
+```
+
+次に、`DataCollatorForCTCWithPadding` をインスタンス化します。
+
+```py
+>>> data_collator = DataCollatorCTCWithPadding(processor=processor, padding="longest")
+```
+
+## Evaluate
+
+トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[単語エラー率](https://huggingface.co/spaces/evaluate-metric/wer) (WER) メトリクスを読み込みます (🤗 Evaluate [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照して、メトリクスをロードして計算する方法の詳細を確認してください)。
+
+```py
+>>> import evaluate
+
+>>> wer = evaluate.load("wer")
+```
+
+次に、予測とラベルを [`~evaluate.EvaluationModule.compute`] に渡して WER を計算する関数を作成します。
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(pred):
+... pred_logits = pred.predictions
+... pred_ids = np.argmax(pred_logits, axis=-1)
+
+... pred.label_ids[pred.label_ids == -100] = processor.tokenizer.pad_token_id
+
+... pred_str = processor.batch_decode(pred_ids)
+... label_str = processor.batch_decode(pred.label_ids, group_tokens=False)
+
+... wer = wer.compute(predictions=pred_str, references=label_str)
+
+... return {"wer": wer}
+```
+
+これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
+
+## Train
+
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[ここ](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForCTC`] で Wav2Vec2 をロードします。 `ctc_loss_reduction` パラメータで適用する削減を指定します。多くの場合、デフォルトの合計ではなく平均を使用する方が適切です。
+
+```py
+>>> from transformers import AutoModelForCTC, TrainingArguments, Trainer
+
+>>> model = AutoModelForCTC.from_pretrained(
+... "facebook/wav2vec2-base",
+... ctc_loss_reduction="mean",
+... pad_token_id=processor.tokenizer.pad_token_id,
+... )
+```
+
+この時点で残っている手順は次の 3 つだけです。
+
+1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`トレーナー`] は WER を評価し、トレーニング チェックポイントを保存します。
+2. トレーニング引数を、モデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Trainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_asr_mind_model",
+... per_device_train_batch_size=8,
+... gradient_accumulation_steps=2,
+... learning_rate=1e-5,
+... warmup_steps=500,
+... max_steps=2000,
+... gradient_checkpointing=True,
+... fp16=True,
+... group_by_length=True,
+... eval_strategy="steps",
+... per_device_eval_batch_size=8,
+... save_steps=1000,
+... eval_steps=1000,
+... logging_steps=25,
+... load_best_model_at_end=True,
+... metric_for_best_model="wer",
+... greater_is_better=False,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=encoded_minds["train"],
+... eval_dataset=encoded_minds["test"],
+... processing_class=processor,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+
+自動音声認識用にモデルを微調整する方法のより詳細な例については、英語 ASR および英語のこのブログ [投稿](https://huggingface.co/blog/fine-tune-wav2vec2-english) を参照してください。多言語 ASR については、この [投稿](https://huggingface.co/blog/fine-tune-xlsr-wav2vec2) を参照してください。
+
+
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+推論を実行したい音声ファイルをロードします。必要に応じて、オーディオ ファイルのサンプリング レートをモデルのサンプリング レートと一致するようにリサンプリングすることを忘れないでください。
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", "en-US", split="train")
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+>>> sampling_rate = dataset.features["audio"].sampling_rate
+>>> audio_file = dataset[0]["audio"]["path"]
+```
+
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して自動音声認識用の`pipeline`をインスタンス化し、オーディオ ファイルをそれに渡します。
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline("automatic-speech-recognition", model="stevhliu/my_awesome_asr_minds_model")
+>>> transcriber(audio_file)
+{'text': 'I WOUD LIKE O SET UP JOINT ACOUNT WTH Y PARTNER'}
+```
+
+
+
+転写はまあまあですが、もっと良くなる可能性があります。さらに良い結果を得るには、より多くの例でモデルを微調整してみてください。
+
+
+
+必要に応じて、「パイプライン」の結果を手動で複製することもできます。
+
+
+
+
+プロセッサをロードしてオーディオ ファイルと文字起こしを前処理し、`input`を PyTorch テンソルとして返します。
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("stevhliu/my_awesome_asr_mind_model")
+>>> inputs = processor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+```
+
+Pass your inputs to the model and return the logits:
+
+```py
+>>> from transformers import AutoModelForCTC
+
+>>> model = AutoModelForCTC.from_pretrained("stevhliu/my_awesome_asr_mind_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+最も高い確率で予測された `input_ids` を取得し、プロセッサを使用して予測された `input_ids` をデコードしてテキストに戻します。
+
+
+```py
+>>> import torch
+
+>>> predicted_ids = torch.argmax(logits, dim=-1)
+>>> transcription = processor.batch_decode(predicted_ids)
+>>> transcription
+['I WOUL LIKE O SET UP JOINT ACOUNT WTH Y PARTNER']
+```
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/audio_classification.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/audio_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..3b33d1b6043d782137c4ba0ec45b5acf2fd343ca
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/audio_classification.md
@@ -0,0 +1,323 @@
+
+
+# Audio classification
+
+[[open-in-colab]]
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/audio-classification) を確認することをお勧めします。
+
+
+
+```bash
+pip install transformers datasets evaluate
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load MInDS-14 dataset
+
+まず、🤗 データセット ライブラリから MInDS-14 データセットをロードします。
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> minds = load_dataset("PolyAI/minds14", name="en-US", split="train")
+```
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train` をより小さなトレインとテスト セットに分割します。これにより、完全なデータセットにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
+
+```py
+>>> minds = minds.train_test_split(test_size=0.2)
+```
+
+次に、データセットを見てみましょう。
+
+```py
+>>> minds
+DatasetDict({
+ train: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 450
+ })
+ test: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 113
+ })
+})
+```
+
+
+データセットには`lang_id`や`english_transcription`などの多くの有用な情報が含まれていますが、このガイドでは`audio`と`intent_class`に焦点を当てます。 [`~datasets.Dataset.remove_columns`] メソッドを使用して他の列を削除します。
+
+```py
+>>> minds = minds.remove_columns(["path", "transcription", "english_transcription", "lang_id"])
+```
+
+ここで例を見てみましょう。
+
+```py
+>>> minds["train"][0]
+{'audio': {'array': array([ 0. , 0. , 0. , ..., -0.00048828,
+ -0.00024414, -0.00024414], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602b9a5fbb1e6d0fbce91f52.wav',
+ 'sampling_rate': 8000},
+ 'intent_class': 2}
+```
+
+次の 2 つのフィールドがあります。
+
+- `audio`: 音声ファイルをロードしてリサンプリングするために呼び出す必要がある音声信号の 1 次元の `array`。
+- `intent_class`: スピーカーのインテントのクラス ID を表します。
+
+モデルがラベル ID からラベル名を取得しやすくするために、ラベル名を整数に、またはその逆にマップする辞書を作成します。
+
+```py
+>>> labels = minds["train"].features["intent_class"].names
+>>> label2id, id2label = dict(), dict()
+>>> for i, label in enumerate(labels):
+... label2id[label] = str(i)
+... id2label[str(i)] = label
+```
+
+これで、ラベル ID をラベル名に変換できるようになりました。
+
+```py
+>>> id2label[str(2)]
+'app_error'
+```
+
+## Preprocess
+
+次のステップでは、Wav2Vec2 特徴抽出プログラムをロードしてオーディオ信号を処理します。
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base")
+```
+
+MInDS-14 データセットのサンプリング レートは 8khz です (この情報は [データセット カード](https://huggingface.co/datasets/PolyAI/minds14) で確認できます)。つまり、データセットを再サンプリングする必要があります。事前トレーニングされた Wav2Vec2 モデルを使用するには、16kHz に設定します。
+
+```py
+>>> minds = minds.cast_column("audio", Audio(sampling_rate=16_000))
+>>> minds["train"][0]
+{'audio': {'array': array([ 2.2098757e-05, 4.6582241e-05, -2.2803260e-05, ...,
+ -2.8419291e-04, -2.3305941e-04, -1.1425107e-04], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602b9a5fbb1e6d0fbce91f52.wav',
+ 'sampling_rate': 16000},
+ 'intent_class': 2}
+```
+
+次に、次の前処理関数を作成します。
+
+1. `audio`列を呼び出してロードし、必要に応じてオーディオ ファイルをリサンプリングします。
+2. オーディオ ファイルのサンプリング レートが、モデルが事前トレーニングされたオーディオ データのサンプリング レートと一致するかどうかを確認します。この情報は、Wav2Vec2 [モデル カード](https://huggingface.co/facebook/wav2vec2-base) で見つけることができます。
+3. 入力の最大長を設定して、長い入力を切り捨てずにバッチ処理します。
+
+```py
+>>> def preprocess_function(examples):
+... audio_arrays = [x["array"] for x in examples["audio"]]
+... inputs = feature_extractor(
+... audio_arrays, sampling_rate=feature_extractor.sampling_rate, max_length=16000, truncation=True
+... )
+... return inputs
+```
+
+データセット全体に前処理関数を適用するには、🤗 Datasets [`~datasets.Dataset.map`] 関数を使用します。 `batched=True` を設定してデータセットの複数の要素を一度に処理することで、`map` を高速化できます。不要な列を削除し、`intent_class` の名前を `label` に変更します。これはモデルが期待する名前であるためです。
+
+```py
+>>> encoded_minds = minds.map(preprocess_function, remove_columns="audio", batched=True)
+>>> encoded_minds = encoded_minds.rename_column("intent_class", "label")
+```
+## Evaluate
+
+トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) メトリクスを読み込みます (🤗 Evaluate [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照してください) メトリクスの読み込みと計算方法の詳細については、次を参照してください。
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+次に、予測とラベルを [`~evaluate.EvaluationModule.compute`] に渡して精度を計算する関数を作成します。
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions = np.argmax(eval_pred.predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=eval_pred.label_ids)
+```
+
+これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
+
+## Train
+
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForAudioClassification`] を使用して、予期されるラベルの数とラベル マッピングを使用して Wav2Vec2 を読み込みます。
+
+```py
+>>> from transformers import AutoModelForAudioClassification, TrainingArguments, Trainer
+
+>>> num_labels = len(id2label)
+>>> model = AutoModelForAudioClassification.from_pretrained(
+... "facebook/wav2vec2-base", num_labels=num_labels, label2id=label2id, id2label=id2label
+... )
+```
+
+この時点で残っている手順は次の 3 つだけです。
+
+1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`トレーナー`] は精度を評価し、トレーニング チェックポイントを保存します。
+2. トレーニング引数を、モデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Trainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_mind_model",
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... learning_rate=3e-5,
+... per_device_train_batch_size=32,
+... gradient_accumulation_steps=4,
+... per_device_eval_batch_size=32,
+... num_train_epochs=10,
+... warmup_ratio=0.1,
+... logging_steps=10,
+... load_best_model_at_end=True,
+... metric_for_best_model="accuracy",
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=encoded_minds["train"],
+... eval_dataset=encoded_minds["test"],
+... processing_class=feature_extractor,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+音声分類用のモデルを微調整する方法の詳細な例については、対応する [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/audio_classification.ipynb).
+
+
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+推論を実行したい音声ファイルをロードします。必要に応じて、オーディオ ファイルのサンプリング レートをモデルのサンプリング レートと一致するようにリサンプリングすることを忘れないでください。
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train")
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+>>> sampling_rate = dataset.features["audio"].sampling_rate
+>>> audio_file = dataset[0]["audio"]["path"]
+```
+
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して音声分類用の`pipeline`をインスタンス化し、それに音声ファイルを渡します。
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("audio-classification", model="stevhliu/my_awesome_minds_model")
+>>> classifier(audio_file)
+[
+ {'score': 0.09766869246959686, 'label': 'cash_deposit'},
+ {'score': 0.07998877018690109, 'label': 'app_error'},
+ {'score': 0.0781070664525032, 'label': 'joint_account'},
+ {'score': 0.07667109370231628, 'label': 'pay_bill'},
+ {'score': 0.0755252093076706, 'label': 'balance'}
+]
+```
+
+必要に応じて、`pipeline` の結果を手動で複製することもできます。
+
+
+
+
+特徴抽出器をロードしてオーディオ ファイルを前処理し、`input`を PyTorch テンソルとして返します。
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("stevhliu/my_awesome_minds_model")
+>>> inputs = feature_extractor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+```
+
+入力をモデルに渡し、ロジットを返します。
+
+```py
+>>> from transformers import AutoModelForAudioClassification
+
+>>> model = AutoModelForAudioClassification.from_pretrained("stevhliu/my_awesome_minds_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+最も高い確率でクラスを取得し、モデルの `id2label` マッピングを使用してそれをラベルに変換します。
+
+```py
+>>> import torch
+
+>>> predicted_class_ids = torch.argmax(logits).item()
+>>> predicted_label = model.config.id2label[predicted_class_ids]
+>>> predicted_label
+'cash_deposit'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/document_question_answering.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/document_question_answering.md
new file mode 100644
index 0000000000000000000000000000000000000000..f07cc6dff28eae20f29a950e6389591a390b9d79
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/document_question_answering.md
@@ -0,0 +1,495 @@
+
+
+# Document Question Answering
+
+[[open-in-colab]]
+
+文書による質問応答は、文書による視覚的な質問応答とも呼ばれ、以下を提供するタスクです。
+ドキュメント画像に関する質問への回答。このタスクをサポートするモデルへの入力は通常、画像と画像の組み合わせです。
+質問があり、出力は自然言語で表現された回答です。これらのモデルは、以下を含む複数のモダリティを利用します。
+テキスト、単語の位置 (境界ボックス)、および画像自体。
+
+このガイドでは、次の方法を説明します。
+
+- [DocVQA データセット](https://huggingface.co/datasets/nielsr/docvqa_1200_examples_donut) の [LayoutLMv2](../model_doc/layoutlmv2) を微調整します。
+- 微調整されたモデルを推論に使用します。
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/image-to-text) を確認することをお勧めします。
+
+
+
+LayoutLMv2 は、最後の非表示のヘッダーの上に質問応答ヘッドを追加することで、ドキュメントの質問応答タスクを解決します。
+トークンの状態を調べて、トークンの開始トークンと終了トークンの位置を予測します。
+答え。言い換えれば、問題は抽出的質問応答として扱われます。つまり、コンテキストを考慮して、どの部分を抽出するかということです。
+の情報が質問に答えます。コンテキストは OCR エンジンの出力から取得されます。ここでは Google の Tesseract です。
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。 LayoutLMv2 は detectron2、torchvision、tesseract に依存します。
+
+```bash
+pip install -q transformers datasets
+```
+
+```bash
+pip install 'git+https://github.com/facebookresearch/detectron2.git'
+pip install torchvision
+```
+
+```bash
+sudo apt install tesseract-ocr
+pip install -q pytesseract
+```
+
+すべての依存関係をインストールしたら、ランタイムを再起動します。
+
+モデルをコミュニティと共有することをお勧めします。 Hugging Face アカウントにログインして、🤗 ハブにアップロードします。
+プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+いくつかのグローバル変数を定義しましょう。
+
+```py
+>>> model_checkpoint = "microsoft/layoutlmv2-base-uncased"
+>>> batch_size = 4
+```
+
+## Load the data
+
+このガイドでは、🤗 Hub にある前処理された DocVQA の小さなサンプルを使用します。フルに使いたい場合は、
+DocVQA データセットは、[DocVQA ホームページ](https://rrc.cvc.uab.es/?ch=17) で登録してダウンロードできます。そうすれば、
+このガイドを進めて、[🤗 データセットにファイルをロードする方法](https://huggingface.co/docs/datasets/loading#local-and-remote-files) を確認してください。
+
+
+```py
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("nielsr/docvqa_1200_examples")
+>>> dataset
+DatasetDict({
+ train: Dataset({
+ features: ['id', 'image', 'query', 'answers', 'words', 'bounding_boxes', 'answer'],
+ num_rows: 1000
+ })
+ test: Dataset({
+ features: ['id', 'image', 'query', 'answers', 'words', 'bounding_boxes', 'answer'],
+ num_rows: 200
+ })
+})
+```
+
+ご覧のとおり、データセットはすでにトレーニング セットとテスト セットに分割されています。理解するためにランダムな例を見てみましょう
+機能を備えた自分自身。
+
+```py
+>>> dataset["train"].features
+```
+
+個々のフィールドが表す内容は次のとおりです。
+* `id`: サンプルのID
+* `image`: ドキュメント画像を含む PIL.Image.Image オブジェクト
+* `query`: 質問文字列 - いくつかの言語での自然言語による質問
+* `answers`: ヒューマン アノテーターによって提供された正解のリスト
+* `words` と `bounding_boxes`: OCR の結果。ここでは使用しません。
+* `answer`: 別のモデルと一致する答え。ここでは使用しません。
+
+英語の質問だけを残し、別のモデルによる予測が含まれていると思われる`answer`機能を削除しましょう。
+また、アノテーターによって提供されたセットから最初の回答を取得します。あるいは、ランダムにサンプリングすることもできます。
+
+```py
+>>> updated_dataset = dataset.map(lambda example: {"question": example["query"]["en"]}, remove_columns=["query"])
+>>> updated_dataset = updated_dataset.map(
+... lambda example: {"answer": example["answers"][0]}, remove_columns=["answer", "answers"]
+... )
+```
+
+このガイドで使用する LayoutLMv2 チェックポイントは、`max_position_embeddings = 512` でトレーニングされていることに注意してください (
+この情報は、[チェックポイントの `config.json` ファイル](https://huggingface.co/microsoft/layoutlmv2-base-uncased/blob/main/config.json#L18)) で見つけてください。
+例を省略することもできますが、答えが大きな文書の最後にあり、結局省略されてしまうという状況を避けるために、
+ここでは、埋め込みが 512 を超える可能性があるいくつかの例を削除します。
+データセット内のほとんどのドキュメントが長い場合は、スライディング ウィンドウ戦略を実装できます。詳細については、[このノートブック](https://github.com/huggingface/notebooks/blob/main/examples/question_answering.ipynb) を確認してください。 。
+
+```py
+>>> updated_dataset = updated_dataset.filter(lambda x: len(x["words"]) + len(x["question"].split()) < 512)
+```
+
+この時点で、このデータセットから OCR 機能も削除しましょう。これらは、異なるデータを微調整するための OCR の結果です。
+モデル。これらは入力要件と一致しないため、使用したい場合はさらに処理が必要になります。
+このガイドで使用するモデルの。代わりに、OCR と OCR の両方の元のデータに対して [`LayoutLMv2Processor`] を使用できます。
+トークン化。このようにして、モデルの予想される入力と一致する入力を取得します。画像を手動で加工したい場合は、
+モデルがどのような入力形式を想定しているかを知るには、[`LayoutLMv2` モデルのドキュメント](../model_doc/layoutlmv2) を確認してください。
+
+```py
+>>> updated_dataset = updated_dataset.remove_columns("words")
+>>> updated_dataset = updated_dataset.remove_columns("bounding_boxes")
+```
+
+最後に、画像サンプルを確認しないとデータ探索は完了しません。
+
+
+```py
+>>> updated_dataset["train"][11]["image"]
+```
+
+
+
+
+量子化されていないバージョンのモデル チェックポイントを使用して次の例を実行するには、少なくとも 20GB の GPU メモリが必要です。
+
+
+## Loading the model
+
+まずはモデルの 90 億個のパラメーターのチェックポイントをロードしましょう。
+
+```py
+>>> checkpoint = "HuggingFaceM4/idefics-9b"
+```
+
+他の Transformers モデルと同様に、プロセッサとモデル自体をチェックポイントからロードする必要があります。
+IDEFICS プロセッサは、[`LlamaTokenizer`] と IDEFICS 画像プロセッサを単一のプロセッサにラップして処理します。
+モデルのテキストと画像の入力を準備します。
+
+
+```py
+>>> import torch
+
+>>> from transformers import IdeficsForVisionText2Text, AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+
+>>> model = IdeficsForVisionText2Text.from_pretrained(checkpoint, torch_dtype=torch.bfloat16, device_map="auto")
+```
+
+`device_map`を`auto`に設定すると、モデルの重みを最も最適化された状態でロードおよび保存する方法が自動的に決定されます。
+既存のデバイスを考慮した方法。
+
+### Quantized model
+
+ハイメモリ GPU の可用性が問題となる場合は、モデルの量子化されたバージョンをロードできます。モデルと
+プロセッサを 4 ビット精度で使用する場合、`BitsAndBytesConfig`を`from_pretrained`メソッドに渡すと、モデルが圧縮されます。
+ロード中にその場で。
+
+
+```py
+>>> import torch
+>>> from transformers import IdeficsForVisionText2Text, AutoProcessor, BitsAndBytesConfig
+
+>>> quantization_config = BitsAndBytesConfig(
+... load_in_4bit=True,
+... bnb_4bit_compute_dtype=torch.float16,
+... )
+
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+
+>>> model = IdeficsForVisionText2Text.from_pretrained(
+... checkpoint,
+... quantization_config=quantization_config,
+... device_map="auto"
+... )
+```
+
+提案された方法のいずれかでモデルをロードしたので、IDEFICS を使用できるタスクの探索に進みましょう。
+
+## Image captioning
+
+画像のキャプション付けは、特定の画像のキャプションを予測するタスクです。一般的な用途は視覚障害者を支援することです
+人々はさまざまな状況をナビゲートします。たとえば、オンラインで画像コンテンツを探索します。
+
+タスクを説明するには、キャプションを付ける画像を取得します。例:
+
+
+
+
", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+A puppy in a flower bed
+```
+
+
+
+増加時に発生するエラーを避けるために、`generate`の呼び出しに`bad_words_ids`を含めることをお勧めします。
+`max_new_tokens`: モデルは、新しい `` または `` トークンを生成する必要があります。
+モデルによって画像が生成されていません。
+このガイドのようにオンザフライで設定することも、[テキスト生成戦略](../generation_strategies) ガイドで説明されているように `GenerationConfig` に保存することもできます。
+
+
+## Prompted image captioning
+
+テキスト プロンプトを提供することで画像キャプションを拡張でき、モデルは画像を指定して続行します。持っていきましょう
+別の図で説明します。
+
+
+
+
", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+This is an image of the Eiffel Tower in Paris, France.
+```
+
+## Few-shot prompting
+
+IDEFICS はゼロショットで優れた結果を示しますが、タスクによっては特定の形式のキャプションが必要になる場合や、キャプションが付属する場合があります。
+タスクの複雑さを増大させるその他の制限または要件。少数のショットのプロンプトを使用して、コンテキスト内の学習を有効にすることができます。
+プロンプトに例を指定することで、指定された例の形式を模倣した結果を生成するようにモデルを操作できます。
+
+前のエッフェル塔の画像をモデルの例として使用し、モデルにデモンストレーションするプロンプトを作成してみましょう。
+画像内のオブジェクトが何であるかを知ることに加えて、それに関する興味深い情報も取得したいと考えています。
+次に、自由の女神の画像に対して同じ応答形式を取得できるかどうかを見てみましょう。
+
+
+
+
", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=30, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+User: Describe this image.
+Assistant: An image of the Eiffel Tower at night. Fun fact: the Eiffel Tower is the same height as an 81-storey building.
+User: Describe this image.
+Assistant: An image of the Statue of Liberty. Fun fact: the Statue of Liberty is 151 feet tall.
+```
+
+モデルは 1 つの例 (つまり、1 ショット) だけからタスクの実行方法を学習していることに注目してください。より複雑なタスクの場合は、
+より多くの例 (3 ショット、5 ショットなど) を自由に試してみてください。
+
+## Visual question answering
+
+Visual Question Answering (VQA) は、画像に基づいて自由形式の質問に答えるタスクです。画像に似ている
+キャプションは、アクセシビリティ アプリケーションだけでなく、教育 (視覚資料についての推論) にも使用できます。
+サービス(画像を基にした商品に関する質問)、画像検索など。
+
+このタスク用に新しい画像を取得しましょう。
+
+
+
+
", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=20, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Provide an answer to the question. Use the image to answer.
+ Question: Where are these people and what's the weather like? Answer: They're in a park in New York City, and it's a beautiful day.
+```
+
+## Image classification
+
+IDEFICS は、次のデータを含むデータについて明示的にトレーニングしなくても、画像をさまざまなカテゴリに分類できます。
+これらの特定のカテゴリからのラベル付きの例。カテゴリのリストを指定し、その画像とテキストを使用して理解する
+機能を利用すると、モデルは画像がどのカテゴリに属する可能性が高いかを推測できます。
+
+たとえば、次のような野菜スタンドの画像があるとします。
+
+
+
+
", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=6, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Classify the following image into a single category from the following list: ['animals', 'vegetables', 'city landscape', 'cars', 'office'].
+Category: Vegetables
+```
+
+上の例では、画像を 1 つのカテゴリに分類するようにモデルに指示していますが、ランク分類を行うようにモデルに指示することもできます。
+
+## Image-guided text generation
+
+よりクリエイティブなアプリケーションの場合は、画像ガイド付きテキスト生成を使用して、画像に基づいてテキストを生成できます。これは可能です
+製品、広告、シーンの説明などを作成するのに役立ちます。
+
+IDEFICS に、赤いドアの単純な画像に基づいてストーリーを書くように促してみましょう。
+
+
+
+
", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, num_beams=2, max_new_tokens=200, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Use the image to write a story.
+ Story:
+Once upon a time, there was a little girl who lived in a house with a red door. She loved her red door. It was the prettiest door in the whole world.
+
+One day, the little girl was playing in her yard when she noticed a man standing on her doorstep. He was wearing a long black coat and a top hat.
+
+The little girl ran inside and told her mother about the man.
+
+Her mother said, “Don’t worry, honey. He’s just a friendly ghost.”
+
+The little girl wasn’t sure if she believed her mother, but she went outside anyway.
+
+When she got to the door, the man was gone.
+
+The next day, the little girl was playing in her yard again when she noticed the man standing on her doorstep.
+
+He was wearing a long black coat and a top hat.
+
+The little girl ran
+```
+
+IDEFICS は玄関先にあるカボチャに気づき、幽霊に関する不気味なハロウィーンの話をしたようです。
+
+
+
+このような長い出力の場合、テキスト生成戦略を微調整すると大きなメリットが得られます。これは役に立ちます
+生成される出力の品質が大幅に向上します。 [テキスト生成戦略](../generation_strategies) を確認してください。
+詳しく知ることができ。
+
+
+
+## Running inference in batch mode
+
+これまでのすべてのセクションでは、IDEFICS を 1 つの例として説明しました。非常に似た方法で、推論を実行できます。
+プロンプトのリストを渡すことにより、サンプルのバッチを取得します。
+
+```py
+>>> prompts = [
+... [ "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
+... "This is an image of ",
+... ],
+... [ "https://images.unsplash.com/photo-1623944889288-cd147dbb517c?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "This is an image of ",
+... ],
+... [ "https://images.unsplash.com/photo-1471193945509-9ad0617afabf?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "This is an image of ",
+... ],
+... ]
+
+>>> inputs = processor(prompts, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> for i,t in enumerate(generated_text):
+... print(f"{i}:\n{t}\n")
+0:
+This is an image of the Eiffel Tower in Paris, France.
+
+1:
+This is an image of a couple on a picnic blanket.
+
+2:
+This is an image of a vegetable stand.
+```
+
+## IDEFICS instruct for conversational use
+
+会話型のユースケースの場合は、🤗 ハブでモデルの微調整された指示されたバージョンを見つけることができます。
+`HuggingFaceM4/idefics-80b-instruct` および `HuggingFaceM4/idefics-9b-instruct`。
+
+これらのチェックポイントは、教師ありモデルと命令モデルを組み合わせたそれぞれの基本モデルを微調整した結果です。
+データセットを微調整することで、ダウンストリームのパフォーマンスを向上させながら、会話設定でモデルをより使いやすくします。
+
+会話での使用とプロンプトは、基本モデルの使用と非常に似ています。
+
+```py
+>>> import torch
+>>> from transformers import IdeficsForVisionText2Text, AutoProcessor
+
+>>> device = "cuda" if torch.cuda.is_available() else "cpu"
+
+>>> checkpoint = "HuggingFaceM4/idefics-9b-instruct"
+>>> model = IdeficsForVisionText2Text.from_pretrained(checkpoint, torch_dtype=torch.bfloat16).to(device)
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+
+>>> prompts = [
+... [
+... "User: What is in this image?",
+... "https://upload.wikimedia.org/wikipedia/commons/8/86/Id%C3%A9fix.JPG",
+... "",
+
+... "\nAssistant: This picture depicts Idefix, the dog of Obelix in Asterix and Obelix. Idefix is running on the ground.",
+
+... "\nUser:",
+... "https://static.wikia.nocookie.net/asterix/images/2/25/R22b.gif/revision/latest?cb=20110815073052",
+... "And who is that?",
+
+... "\nAssistant:",
+... ],
+... ]
+
+>>> # --batched mode
+>>> inputs = processor(prompts, add_end_of_utterance_token=False, return_tensors="pt").to(device)
+>>> # --single sample mode
+>>> # inputs = processor(prompts[0], return_tensors="pt").to(device)
+
+>>> # Generation args
+>>> exit_condition = processor.tokenizer("", add_special_tokens=False).input_ids
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, eos_token_id=exit_condition, bad_words_ids=bad_words_ids, max_length=100)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> for i, t in enumerate(generated_text):
+... print(f"{i}:\n{t}\n")
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/image_captioning.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/image_captioning.md
new file mode 100644
index 0000000000000000000000000000000000000000..7649947b2c6450110c60ad6f6d7f4a5ad2a9d49d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/image_captioning.md
@@ -0,0 +1,276 @@
+
+
+# Image captioning
+
+[[open-in-colab]]
+
+画像のキャプション付けは、特定の画像のキャプションを予測するタスクです。一般的な現実世界のアプリケーションには次のものがあります。
+視覚障害者がさまざまな状況を乗り越えられるよう支援します。したがって、画像のキャプション
+画像を説明することで人々のコンテンツへのアクセシビリティを向上させるのに役立ちます。
+
+このガイドでは、次の方法を説明します。
+
+* 画像キャプション モデルを微調整します。
+* 微調整されたモデルを推論に使用します。
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install transformers datasets evaluate -q
+pip install jiwer -q
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+
+```python
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+## Load the Pokémon BLIP captions dataset
+
+🤗 データセット ライブラリを使用して、{image-caption} ペアで構成されるデータセットを読み込みます。独自の画像キャプション データセットを作成するには
+PyTorch では、[このノートブック](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/GIT/Fine_tune_GIT_on_an_image_captioning_dataset.ipynb) を参照できます。
+
+```py
+ds = load_dataset("lambdalabs/pokemon-blip-captions")
+ds
+```
+
+```bash
+DatasetDict({
+ train: Dataset({
+ features: ['image', 'text'],
+ num_rows: 833
+ })
+})
+```
+
+データセットには `image`と`text`の 2 つの機能があります。
+
+
+
+多くの画像キャプション データセットには、画像ごとに複数のキャプションが含まれています。このような場合、一般的な戦略は、トレーニング中に利用可能なキャプションの中からランダムにキャプションをサンプリングすることです。
+
+
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットのトレイン スプリットをトレイン セットとテスト セットに分割します。
+
+```python
+ds = ds["train"].train_test_split(test_size=0.1)
+train_ds = ds["train"]
+test_ds = ds["test"]
+```
+
+トレーニング セットからのいくつかのサンプルを視覚化してみましょう。
+
+```python
+from textwrap import wrap
+import matplotlib.pyplot as plt
+import numpy as np
+
+
+def plot_images(images, captions):
+ plt.figure(figsize=(20, 20))
+ for i in range(len(images)):
+ ax = plt.subplot(1, len(images), i + 1)
+ caption = captions[i]
+ caption = "\n".join(wrap(caption, 12))
+ plt.title(caption)
+ plt.imshow(images[i])
+ plt.axis("off")
+
+
+sample_images_to_visualize = [np.array(train_ds[i]["image"]) for i in range(5)]
+sample_captions = [train_ds[i]["text"] for i in range(5)]
+plot_images(sample_images_to_visualize, sample_captions)
+```
+
+
+
+
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/image-classification) を確認することをお勧めします。
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install transformers datasets evaluate
+```
+
+Hugging Face アカウントにログインして、モデルをアップロードしてコミュニティと共有することをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load Food-101 dataset
+
+Datasets、🤗 データセット ライブラリから Food-101 データセットの小さいサブセットを読み込みます。これにより、次の機会が得られます
+完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認してください。
+
+```py
+>>> from datasets import load_dataset
+
+>>> food = load_dataset("food101", split="train[:5000]")
+```
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train` 分割をトレイン セットとテスト セットに分割します。
+
+
+```py
+>>> food = food.train_test_split(test_size=0.2)
+```
+
+次に、例を見てみましょう。
+
+```py
+>>> food["train"][0]
+{'image': ,
+ 'label': 79}
+```
+
+データセット内の各例には 2 つのフィールドがあります。
+
+- `image`: 食品の PIL 画像
+- `label`: 食品のラベルクラス
+
+モデルがラベル ID からラベル名を取得しやすくするために、ラベル名をマップする辞書を作成します。
+整数への変換、またはその逆:
+
+```py
+>>> labels = food["train"].features["label"].names
+>>> label2id, id2label = dict(), dict()
+>>> for i, label in enumerate(labels):
+... label2id[label] = str(i)
+... id2label[str(i)] = label
+```
+
+これで、ラベル ID をラベル名に変換できるようになりました。
+
+```py
+>>> id2label[str(79)]
+'prime_rib'
+```
+
+## Preprocess
+
+次のステップでは、ViT 画像プロセッサをロードして画像をテンソルに処理します。
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> checkpoint = "google/vit-base-patch16-224-in21k"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
+```
+
+
+
+
+
+いくつかの画像変換を画像に適用して、モデルの過学習に対する堅牢性を高めます。ここでは torchvision の [`transforms`](https://pytorch.org/vision/stable/transforms.html) モジュールを使用しますが、任意の画像ライブラリを使用することもできます。
+
+画像のランダムな部分をトリミングし、サイズを変更し、画像の平均と標準偏差で正規化します。
+
+
+```py
+>>> from torchvision.transforms import RandomResizedCrop, Compose, Normalize, ToTensor
+
+>>> normalize = Normalize(mean=image_processor.image_mean, std=image_processor.image_std)
+>>> size = (
+... image_processor.size["shortest_edge"]
+... if "shortest_edge" in image_processor.size
+... else (image_processor.size["height"], image_processor.size["width"])
+... )
+>>> _transforms = Compose([RandomResizedCrop(size), ToTensor(), normalize])
+```
+
+次に、変換を適用し、画像の `pixel_values` (モデルへの入力) を返す前処理関数を作成します。
+
+```py
+>>> def transforms(examples):
+... examples["pixel_values"] = [_transforms(img.convert("RGB")) for img in examples["image"]]
+... del examples["image"]
+... return examples
+```
+
+データセット全体に前処理関数を適用するには、🤗 Datasets [`~datasets.Dataset.with_transform`] メソッドを使用します。変換は、データセットの要素を読み込むときにオンザフライで適用されます。
+
+```py
+>>> food = food.with_transform(transforms)
+```
+
+次に、[`DefaultDataCollator`] を使用してサンプルのバッチを作成します。 🤗 Transformers の他のデータ照合器とは異なり、`DefaultDataCollator` はパディングなどの追加の前処理を適用しません。
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+
+
+
+
+
+
+過剰適合を回避し、モデルをより堅牢にするために、データセットのトレーニング部分にデータ拡張を追加します。
+ここでは、Keras 前処理レイヤーを使用してトレーニング データの変換 (データ拡張を含む) を定義します。
+検証データの変換 (中央のトリミング、サイズ変更、正規化のみ)。 `tf.image` または
+他のライブラリでも構いません。
+
+
+```py
+>>> from tensorflow import keras
+>>> from tensorflow.keras import layers
+
+>>> size = (image_processor.size["height"], image_processor.size["width"])
+
+>>> train_data_augmentation = keras.Sequential(
+... [
+... layers.RandomCrop(size[0], size[1]),
+... layers.Rescaling(scale=1.0 / 127.5, offset=-1),
+... layers.RandomFlip("horizontal"),
+... layers.RandomRotation(factor=0.02),
+... layers.RandomZoom(height_factor=0.2, width_factor=0.2),
+... ],
+... name="train_data_augmentation",
+... )
+
+>>> val_data_augmentation = keras.Sequential(
+... [
+... layers.CenterCrop(size[0], size[1]),
+... layers.Rescaling(scale=1.0 / 127.5, offset=-1),
+... ],
+... name="val_data_augmentation",
+... )
+```
+
+次に、一度に 1 つの画像ではなく、画像のバッチに適切な変換を適用する関数を作成します。
+
+```py
+>>> import numpy as np
+>>> import tensorflow as tf
+>>> from PIL import Image
+
+
+>>> def convert_to_tf_tensor(image: Image):
+... np_image = np.array(image)
+... tf_image = tf.convert_to_tensor(np_image)
+... # `expand_dims()` is used to add a batch dimension since
+... # the TF augmentation layers operates on batched inputs.
+... return tf.expand_dims(tf_image, 0)
+
+
+>>> def preprocess_train(example_batch):
+... """Apply train_transforms across a batch."""
+... images = [
+... train_data_augmentation(convert_to_tf_tensor(image.convert("RGB"))) for image in example_batch["image"]
+... ]
+... example_batch["pixel_values"] = [tf.transpose(tf.squeeze(image)) for image in images]
+... return example_batch
+
+
+... def preprocess_val(example_batch):
+... """Apply val_transforms across a batch."""
+... images = [
+... val_data_augmentation(convert_to_tf_tensor(image.convert("RGB"))) for image in example_batch["image"]
+... ]
+... example_batch["pixel_values"] = [tf.transpose(tf.squeeze(image)) for image in images]
+... return example_batch
+```
+
+🤗 データセット [`~datasets.Dataset.set_transform`] を使用して、その場で変換を適用します。
+
+```py
+food["train"].set_transform(preprocess_train)
+food["test"].set_transform(preprocess_val)
+```
+
+最後の前処理ステップとして、`DefaultDataCollator`を使用してサンプルのバッチを作成します。 🤗 Transformers の他のデータ照合機能とは異なり、
+`DefaultDataCollator` は、パディングなどの追加の前処理を適用しません。
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。すぐにロードできます
+🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用した評価方法。このタスクでは、ロードします
+[accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) 指標 (詳細については、🤗 評価 [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照してくださいメトリクスをロードして計算する方法):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+次に、予測とラベルを [`~evaluate.EvaluationModule.compute`] に渡して精度を計算する関数を作成します。
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... predictions = np.argmax(predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=labels)
+```
+
+これで `compute_metrics`関数の準備が整いました。トレーニングを設定するときにこの関数に戻ります。
+
+## Train
+
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForImageClassification`] を使用して ViT をロードします。ラベルの数と予想されるラベルの数、およびラベル マッピングを指定します。
+
+```py
+>>> from transformers import AutoModelForImageClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForImageClassification.from_pretrained(
+... checkpoint,
+... num_labels=len(labels),
+... id2label=id2label,
+... label2id=label2id,
+... )
+```
+
+この時点で残っているステップは 3 つだけです。
+
+1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。 `image` 列が削除されるため、未使用の列を削除しないことが重要です。 `image` 列がないと、`pixel_values` を作成できません。この動作を防ぐには、`remove_unused_columns=False`を設定してください。他に必要なパラメータは、モデルの保存場所を指定する `output_dir` だけです。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`Trainer`] は精度を評価し、トレーニング チェックポイントを保存します。
+2. トレーニング引数を、モデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Trainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_food_model",
+... remove_unused_columns=False,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... learning_rate=5e-5,
+... per_device_train_batch_size=16,
+... gradient_accumulation_steps=4,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... warmup_ratio=0.1,
+... logging_steps=10,
+... load_best_model_at_end=True,
+... metric_for_best_model="accuracy",
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... data_collator=data_collator,
+... train_dataset=food["train"],
+... eval_dataset=food["test"],
+... processing_class=image_processor,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+
+
+
+
+Keras を使用したモデルの微調整に慣れていない場合は、まず [基本チュートリアル](./training#train-a-tensorflow-model-with-keras) を確認してください。
+
+
+
+
+TensorFlow でモデルを微調整するには、次の手順に従います。
+1. トレーニングのハイパーパラメータを定義し、オプティマイザーと学習率スケジュールを設定します。
+2. 事前トレーニングされたモデルをインスタンス化します。
+3. 🤗 データセットを `tf.data.Dataset` に変換します。
+4. モデルをコンパイルします。
+5. コールバックを追加し、`fit()` メソッドを使用してトレーニングを実行します。
+6. モデルを 🤗 Hub にアップロードしてコミュニティと共有します。
+
+まず、ハイパーパラメーター、オプティマイザー、学習率スケジュールを定義します。
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_epochs = 5
+>>> num_train_steps = len(food["train"]) * num_epochs
+>>> learning_rate = 3e-5
+>>> weight_decay_rate = 0.01
+
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=learning_rate,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=weight_decay_rate,
+... num_warmup_steps=0,
+... )
+```
+
+次に、ラベル マッピングとともに [`TFAutoModelForImageClassification`] を使用して ViT を読み込みます。
+
+```py
+>>> from transformers import TFAutoModelForImageClassification
+
+>>> model = TFAutoModelForImageClassification.from_pretrained(
+... checkpoint,
+... id2label=id2label,
+... label2id=label2id,
+... )
+```
+
+Convert your datasets to the `tf.data.Dataset` format using the [`~datasets.Dataset.to_tf_dataset`] and your `data_collator`:
+
+```py
+>>> # converting our train dataset to tf.data.Dataset
+>>> tf_train_dataset = food["train"].to_tf_dataset(
+... columns="pixel_values", label_cols="label", shuffle=True, batch_size=batch_size, collate_fn=data_collator
+... )
+
+>>> # converting our test dataset to tf.data.Dataset
+>>> tf_eval_dataset = food["test"].to_tf_dataset(
+... columns="pixel_values", label_cols="label", shuffle=True, batch_size=batch_size, collate_fn=data_collator
+... )
+```
+
+`compile()` を使用してトレーニング用にモデルを設定します。
+
+```py
+>>> from tensorflow.keras.losses import SparseCategoricalCrossentropy
+
+>>> loss = tf.keras.losses.SparseCategoricalCrossentropy(from_logits=True)
+>>> model.compile(optimizer=optimizer, loss=loss)
+```
+
+予測から精度を計算し、モデルを 🤗 ハブにプッシュするには、[Keras callbacks](../main_classes/keras_callbacks) を使用します。
+`compute_metrics` 関数を [KerasMetricCallback](../main_classes/keras_callbacks#transformers.KerasMetricCallback) に渡します。
+[PushToHubCallback](../main_classes/keras_callbacks#transformers.PushToHubCallback) を使用してモデルをアップロードします。
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback, PushToHubCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_eval_dataset)
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="food_classifier",
+... tokenizer=image_processor,
+... save_strategy="no",
+... )
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+ついに、モデルをトレーニングする準備が整いました。トレーニングおよび検証データセット、エポック数、
+モデルを微調整するためのコールバック:
+
+```py
+>>> model.fit(tf_train_dataset, validation_data=tf_eval_dataset, epochs=num_epochs, callbacks=callbacks)
+Epoch 1/5
+250/250 [==============================] - 313s 1s/step - loss: 2.5623 - val_loss: 1.4161 - accuracy: 0.9290
+Epoch 2/5
+250/250 [==============================] - 265s 1s/step - loss: 0.9181 - val_loss: 0.6808 - accuracy: 0.9690
+Epoch 3/5
+250/250 [==============================] - 252s 1s/step - loss: 0.3910 - val_loss: 0.4303 - accuracy: 0.9820
+Epoch 4/5
+250/250 [==============================] - 251s 1s/step - loss: 0.2028 - val_loss: 0.3191 - accuracy: 0.9900
+Epoch 5/5
+250/250 [==============================] - 238s 949ms/step - loss: 0.1232 - val_loss: 0.3259 - accuracy: 0.9890
+```
+
+おめでとう!モデルを微調整し、🤗 Hub で共有しました。これで推論に使用できるようになりました。
+
+
+
+
+
+
+画像分類用のモデルを微調整する方法の詳細な例については、対応する [PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb)
+
+
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+推論を実行したい画像を読み込みます。
+
+```py
+>>> ds = load_dataset("food101", split="validation[:10]")
+>>> image = ds["image"][0]
+```
+
+
+
+
+
+
+画像プロセッサをロードして画像を前処理し、`input`を PyTorch テンソルとして返します。
+
+```py
+>>> from transformers import AutoImageProcessor
+>>> import torch
+
+>>> image_processor = AutoImageProcessor.from_pretrained("my_awesome_food_model")
+>>> inputs = image_processor(image, return_tensors="pt")
+```
+
+入力をモデルに渡し、ロジットを返します。
+
+```py
+>>> from transformers import AutoModelForImageClassification
+
+>>> model = AutoModelForImageClassification.from_pretrained("my_awesome_food_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+最も高い確率で予測されたラベルを取得し、モデルの `id2label` マッピングを使用してラベルに変換します。
+
+```py
+>>> predicted_label = logits.argmax(-1).item()
+>>> model.config.id2label[predicted_label]
+'beignets'
+```
+
+
+
+
+
+
+画像プロセッサをロードして画像を前処理し、`input`を TensorFlow テンソルとして返します。
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("MariaK/food_classifier")
+>>> inputs = image_processor(image, return_tensors="tf")
+```
+
+入力をモデルに渡し、ロジットを返します。
+
+```py
+>>> from transformers import TFAutoModelForImageClassification
+
+>>> model = TFAutoModelForImageClassification.from_pretrained("MariaK/food_classifier")
+>>> logits = model(**inputs).logits
+```
+
+最も高い確率で予測されたラベルを取得し、モデルの `id2label` マッピングを使用してラベルに変換します。
+
+
+```py
+>>> predicted_class_id = int(tf.math.argmax(logits, axis=-1)[0])
+>>> model.config.id2label[predicted_class_id]
+'beignets'
+```
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/image_to_image.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/image_to_image.md
new file mode 100644
index 0000000000000000000000000000000000000000..cd429a4e1e27c3281d823683768eb2bac101e197
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/image_to_image.md
@@ -0,0 +1,135 @@
+
+
+# Image-to-Image Task Guide
+
+[[open-in-colab]]
+
+Image-to-Image タスクは、アプリケーションが画像を受信し、別の画像を出力するタスクです。これには、画像強化 (超解像度、低光量強化、ディレインなど)、画像修復などを含むさまざまなサブタスクがあります。
+
+このガイドでは、次の方法を説明します。
+- 超解像度タスクに画像間のパイプラインを使用します。
+- パイプラインを使用せずに、同じタスクに対してイメージ間モデルを実行します。
+
+このガイドがリリースされた時点では、`image-to-image`パイプラインは超解像度タスクのみをサポートしていることに注意してください。
+
+必要なライブラリをインストールすることから始めましょう。
+
+```bash
+pip install transformers
+```
+
+[Swin2SR モデル](https://huggingface.co/caidas/swin2SR-lightweight-x2-64) を使用してパイプラインを初期化できるようになりました。次に、イメージを使用してパイプラインを呼び出すことで、パイプラインを推論できます。現時点では、[Swin2SR モデル](https://huggingface.co/models?sort=trending&search=swin2sr) のみがこのパイプラインでサポートされています。
+
+```python
+from transformers import pipeline
+
+device = torch.device('cuda' if torch.cuda.is_available() else 'cpu')
+pipe = pipeline(task="image-to-image", model="caidas/swin2SR-lightweight-x2-64", device=device)
+```
+
+では、画像を読み込みましょう。
+
+```python
+from PIL import Image
+import requests
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/cat.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+print(image.size)
+```
+```bash
+# (532, 432)
+```
+
+
+
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/text-generation) を確認することをお勧めします。u
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install transformers datasets evaluate
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load ELI5 dataset
+
+
+まず、ELI5 データセットの r/askscience サブセットの小さいサブセットを 🤗 データセット ライブラリからロードします。
+ これにより、完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
+
+```py
+>>> from datasets import load_dataset
+
+>>> eli5 = load_dataset("eli5", split="train_asks[:5000]")
+```
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train_asks` をトレイン セットとテスト セットに分割します。
+
+```py
+>>> eli5 = eli5.train_test_split(test_size=0.2)
+```
+
+次に、例を見てみましょう。
+
+```py
+>>> eli5["train"][0]
+{'answers': {'a_id': ['c3d1aib', 'c3d4lya'],
+ 'score': [6, 3],
+ 'text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
+ "Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"]},
+ 'answers_urls': {'url': []},
+ 'document': '',
+ 'q_id': 'nyxfp',
+ 'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
+ 'selftext_urls': {'url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg']},
+ 'subreddit': 'askscience',
+ 'title': 'Few questions about this space walk photograph.',
+ 'title_urls': {'url': []}}
+```
+
+これは多くのことのように見えるかもしれませんが、実際に関心があるのは`text`フィールドだけです。言語モデリングの優れている点
+タスクでは、次の単語がラベル * であるため、ラベル (教師なしタスクとも呼ばれます) は必要ありません。
+
+
+## Preprocess
+
+
+
+
+シーケンス終了トークンをパディング トークンとして使用し、`mlm=False` を設定します。これは、入力を 1 要素分右にシフトしたラベルとして使用します。
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> tokenizer.pad_token = tokenizer.eos_token
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False)
+```
+
+
+
+シーケンス終了トークンをパディング トークンとして使用し、`mlm=False` を設定します。これは、入力を 1 要素分右にシフトしたラベルとして使用します。
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False, return_tensors="tf")
+```
+
+
+
+
+
+## Train
+
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[基本チュートリアル](../training#train-with-pytorch-trainer) を参照してください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForCausalLM`] を使用して DistilGPT2 をロードします。
+
+
+```py
+>>> from transformers import AutoModelForCausalLM, TrainingArguments, Trainer
+
+>>> model = AutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+この時点で残っている手順は次の 3 つだけです。
+
+1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。
+2. トレーニング引数をモデル、データセット、データ照合器とともに [`Trainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_eli5_clm-model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=lm_dataset["train"],
+... eval_dataset=lm_dataset["test"],
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.evaluate`] メソッドを使用してモデルを評価し、その複雑さを取得します。
+
+```py
+>>> import math
+
+>>> eval_results = trainer.evaluate()
+>>> print(f"Perplexity: {math.exp(eval_results['eval_loss']):.2f}")
+Perplexity: 49.61
+```
+
+次に、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras を使用したモデルの微調整に慣れていない場合は、[基本チュートリアル](../training#train-a-tensorflow-model-with-keras) をご覧ください。
+
+
+TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+次に、[`TFAutoModelForCausalLM`] を使用して DistilGPT2 をロードできます。
+
+```py
+>>> from transformers import TFAutoModelForCausalLM
+
+>>> model = TFAutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... lm_dataset["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... lm_dataset["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+これは、モデルとトークナイザーを [`~transformers.PushToHubCallback`] でプッシュする場所を指定することで実行できます。
+
+
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_eli5_clm-model",
+... tokenizer=tokenizer,
+... )
+```
+
+ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
+
+
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=[callback])
+```
+
+トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
+
+
+
+
+
+
+因果言語モデリング用にモデルを微調整する方法のより詳細な例については、対応するドキュメントを参照してください。
+[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)
+または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)。
+
+
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+テキストを生成するプロンプトを考え出します。
+
+```py
+>>> prompt = "Somatic hypermutation allows the immune system to"
+```
+
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用してテキスト生成用の`pipeline`をインスタンス化し、それにテキストを渡します。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline("text-generation", model="my_awesome_eli5_clm-model")
+>>> generator(prompt)
+[{'generated_text': "Somatic hypermutation allows the immune system to be able to effectively reverse the damage caused by an infection.\n\n\nThe damage caused by an infection is caused by the immune system's ability to perform its own self-correcting tasks."}]
+```
+
+
+
+
+
+テキストをトークン化し、「input_ids」を PyTorch テンソルとして返します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_clm-model")
+>>> inputs = tokenizer(prompt, return_tensors="pt").input_ids
+```
+
+[`~generation.GenerationMixin.generate`] メソッドを使用してテキストを生成します。
+さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[テキスト生成戦略](../generation_strategies) ページを参照してください。
+
+```py
+>>> from transformers import AutoModelForCausalLM
+
+>>> model = AutoModelForCausalLM.from_pretrained("my_awesome_eli5_clm-model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=True, top_k=50, top_p=0.95)
+```
+
+生成されたトークン ID をデコードしてテキストに戻します。
+
+```py
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+["Somatic hypermutation allows the immune system to react to drugs with the ability to adapt to a different environmental situation. In other words, a system of 'hypermutation' can help the immune system to adapt to a different environmental situation or in some cases even a single life. In contrast, researchers at the University of Massachusetts-Boston have found that 'hypermutation' is much stronger in mice than in humans but can be found in humans, and that it's not completely unknown to the immune system. A study on how the immune system"]
+```
+
+
+
+
+テキストをトークン化し、`input_ids`を TensorFlow テンソルとして返します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_clm-model")
+>>> inputs = tokenizer(prompt, return_tensors="tf").input_ids
+```
+
+[`~transformers.generation_tf_utils.TFGenerationMixin.generate`] メソッドを使用して要約を作成します。さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[テキスト生成戦略](../generation_strategies) ページを参照してください。
+
+```py
+>>> from transformers import TFAutoModelForCausalLM
+
+>>> model = TFAutoModelForCausalLM.from_pretrained("my_awesome_eli5_clm-model")
+>>> outputs = model.generate(input_ids=inputs, max_new_tokens=100, do_sample=True, top_k=50, top_p=0.95)
+```
+
+生成されたトークン ID をデコードしてテキストに戻します。
+
+```py
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Somatic hypermutation allows the immune system to detect the presence of other viruses as they become more prevalent. Therefore, researchers have identified a high proportion of human viruses. The proportion of virus-associated viruses in our study increases with age. Therefore, we propose a simple algorithm to detect the presence of these new viruses in our samples as a sign of improved immunity. A first study based on this algorithm, which will be published in Science on Friday, aims to show that this finding could translate into the development of a better vaccine that is more effective for']
+```
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/masked_language_modeling.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/masked_language_modeling.md
new file mode 100644
index 0000000000000000000000000000000000000000..29d7b73ae5d026f210de5c9d82401224a4a94bda
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/masked_language_modeling.md
@@ -0,0 +1,449 @@
+
+
+# Masked language modeling
+
+[[open-in-colab]]
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/fill-mask) を確認することをお勧めします。
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install transformers datasets evaluate
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load ELI5 dataset
+
+まず、ELI5 データセットの r/askscience サブセットの小さいサブセットを 🤗 データセット ライブラリからロードします。これで
+データセット全体のトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が与えられます。
+
+```py
+>>> from datasets import load_dataset
+
+>>> eli5 = load_dataset("eli5", split="train_asks[:5000]")
+```
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train_asks` をトレイン セットとテスト セットに分割します。
+
+```py
+>>> eli5 = eli5.train_test_split(test_size=0.2)
+```
+
+次に、例を見てみましょう。
+
+```py
+>>> eli5["train"][0]
+{'answers': {'a_id': ['c3d1aib', 'c3d4lya'],
+ 'score': [6, 3],
+ 'text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
+ "Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"]},
+ 'answers_urls': {'url': []},
+ 'document': '',
+ 'q_id': 'nyxfp',
+ 'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
+ 'selftext_urls': {'url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg']},
+ 'subreddit': 'askscience',
+ 'title': 'Few questions about this space walk photograph.',
+ 'title_urls': {'url': []}}
+```
+
+これは多くのことのように見えるかもしれませんが、実際に関心があるのは`text`フィールドだけです。言語モデリング タスクの優れた点は、次の単語がラベル * であるため、ラベル (教師なしタスクとも呼ばれます) が必要ないことです。
+
+## Preprocess
+
+
+
+
+シーケンス終了トークンをパディング トークンとして使用し、データを反復するたびにランダムにトークンをマスクするために `mlm_probability` を指定します。
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> tokenizer.pad_token = tokenizer.eos_token
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=0.15)
+```
+
+
+
+シーケンス終了トークンをパディング トークンとして使用し、データを反復するたびにランダムにトークンをマスクするために `mlm_probability` を指定します。
+
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=0.15, return_tensors="tf")
+```
+
+
+
+## Train
+
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[ここ](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForMaskedLM`] を使用して DistilRoBERTa をロードします。
+
+```py
+>>> from transformers import AutoModelForMaskedLM
+
+>>> model = AutoModelForMaskedLM.from_pretrained("distilbert/distilroberta-base")
+```
+
+この時点で残っている手順は次の 3 つだけです。
+
+1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。
+2. トレーニング引数をモデル、データセット、データ照合器とともに [`Trainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_eli5_mlm_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=lm_dataset["train"],
+... eval_dataset=lm_dataset["test"],
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.evaluate`] メソッドを使用してモデルを評価し、その複雑さを取得します。
+
+
+```py
+>>> import math
+
+>>> eval_results = trainer.evaluate()
+>>> print(f"Perplexity: {math.exp(eval_results['eval_loss']):.2f}")
+Perplexity: 8.76
+```
+
+次に、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+Keras を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-a-tensorflow-model-with-keras) の基本的なチュートリアルをご覧ください。
+
+
+
+TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+次に、[`TFAutoModelForMaskedLM`] を使用して DistilRoBERTa をロードできます。
+
+```py
+>>> from transformers import TFAutoModelForMaskedLM
+
+>>> model = TFAutoModelForMaskedLM.from_pretrained("distilbert/distilroberta-base")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... lm_dataset["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... lm_dataset["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
+
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+This can be done by specifying where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_eli5_mlm_model",
+... tokenizer=tokenizer,
+... )
+```
+
+ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
+
+
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=[callback])
+```
+
+トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
+
+
+
+
+
+
+マスクされた言語モデリング用にモデルを微調整する方法のより詳細な例については、対応するドキュメントを参照してください。
+[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)
+または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)。
+
+
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+モデルに空白を埋めるテキストを考え出し、特別な `` トークンを使用して空白を示します。
+
+```py
+>>> text = "The Milky Way is a galaxy."
+```
+
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用してフィルマスクの`pipeline`をインスタンス化し、テキストをそれに渡します。必要に応じて、`top_k`パラメータを使用して、返す予測の数を指定できます。
+
+```py
+>>> from transformers import pipeline
+
+>>> mask_filler = pipeline("fill-mask", "stevhliu/my_awesome_eli5_mlm_model")
+>>> mask_filler(text, top_k=3)
+[{'score': 0.5150994658470154,
+ 'token': 21300,
+ 'token_str': ' spiral',
+ 'sequence': 'The Milky Way is a spiral galaxy.'},
+ {'score': 0.07087188959121704,
+ 'token': 2232,
+ 'token_str': ' massive',
+ 'sequence': 'The Milky Way is a massive galaxy.'},
+ {'score': 0.06434620916843414,
+ 'token': 650,
+ 'token_str': ' small',
+ 'sequence': 'The Milky Way is a small galaxy.'}]
+```
+
+
+
+
+テキストをトークン化し、`input_ids`を PyTorch テンソルとして返します。 `` トークンの位置も指定する必要があります。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+>>> mask_token_index = torch.where(inputs["input_ids"] == tokenizer.mask_token_id)[1]
+```
+
+入力をモデルに渡し、マスクされたトークンの`logits`を返します。
+
+```py
+>>> from transformers import AutoModelForMaskedLM
+
+>>> model = AutoModelForMaskedLM.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
+>>> logits = model(**inputs).logits
+>>> mask_token_logits = logits[0, mask_token_index, :]
+```
+
+次に、マスクされた 3 つのトークンを最も高い確率で返し、出力します。
+
+```py
+>>> top_3_tokens = torch.topk(mask_token_logits, 3, dim=1).indices[0].tolist()
+
+>>> for token in top_3_tokens:
+... print(text.replace(tokenizer.mask_token, tokenizer.decode([token])))
+The Milky Way is a spiral galaxy.
+The Milky Way is a massive galaxy.
+The Milky Way is a small galaxy.
+```
+
+
+
+
+テキストをトークン化し、`input_ids`を TensorFlow テンソルとして返します。 `` トークンの位置も指定する必要があります。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+>>> mask_token_index = tf.where(inputs["input_ids"] == tokenizer.mask_token_id)[0, 1]
+```
+
+入力をモデルに渡し、マスクされたトークンの`logits`を返します。
+
+
+```py
+>>> from transformers import TFAutoModelForMaskedLM
+
+>>> model = TFAutoModelForMaskedLM.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
+>>> logits = model(**inputs).logits
+>>> mask_token_logits = logits[0, mask_token_index, :]
+```
+
+次に、マスクされた 3 つのトークンを最も高い確率で返し、出力します。
+
+
+```py
+>>> top_3_tokens = tf.math.top_k(mask_token_logits, 3).indices.numpy()
+
+>>> for token in top_3_tokens:
+... print(text.replace(tokenizer.mask_token, tokenizer.decode([token])))
+The Milky Way is a spiral galaxy.
+The Milky Way is a massive galaxy.
+The Milky Way is a small galaxy.
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/monocular_depth_estimation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/monocular_depth_estimation.md
new file mode 100644
index 0000000000000000000000000000000000000000..e7a3a994a60ebc3ee752cfd0461bb7436c7b8406
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/monocular_depth_estimation.md
@@ -0,0 +1,149 @@
+
+
+# Monocular depth estimation
+
+単眼奥行き推定は、シーンの奥行き情報を画像から予測することを含むコンピューター ビジョン タスクです。
+単一の画像。言い換えれば、シーン内のオブジェクトの距離を距離から推定するプロセスです。
+単一カメラの視点。
+
+単眼奥行き推定には、3D 再構築、拡張現実、自動運転、
+そしてロボット工学。モデルがオブジェクト間の複雑な関係を理解する必要があるため、これは困難な作業です。
+シーンとそれに対応する深度情報(照明条件などの要因の影響を受ける可能性があります)
+オクルージョンとテクスチャ。
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/depth-estimation) を確認することをお勧めします。
+
+
+
+このガイドでは、次の方法を学びます。
+
+* 深度推定パイプラインを作成する
+* 手動で深度推定推論を実行します
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install -q transformers
+```
+
+## Depth estimation pipeline
+
+深度推定をサポートするモデルで推論を試す最も簡単な方法は、対応する [`pipeline`] を使用することです。
+[Hugging Face Hub のチェックポイント](https://huggingface.co/models?pipeline_tag=Depth-estimation&sort=downloads) からパイプラインをインスタンス化します。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> checkpoint = "vinvino02/glpn-nyu"
+>>> depth_estimator = pipeline("depth-estimation", model=checkpoint)
+```
+
+次に、分析する画像を選択します。
+
+```py
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "https://unsplash.com/photos/HwBAsSbPBDU/download?ixid=MnwxMjA3fDB8MXxzZWFyY2h8MzR8fGNhciUyMGluJTIwdGhlJTIwc3RyZWV0fGVufDB8MHx8fDE2Nzg5MDEwODg&force=true&w=640"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> image
+```
+
+
+
+
+
+
+
+
+
+```py
+>>> from dataclasses import dataclass
+>>> from transformers.tokenization_utils_base import PreTrainedTokenizerBase, PaddingStrategy
+>>> from typing import Optional, Union
+>>> import torch
+
+
+>>> @dataclass
+... class DataCollatorForMultipleChoice:
+... """
+... Data collator that will dynamically pad the inputs for multiple choice received.
+... """
+
+... tokenizer: PreTrainedTokenizerBase
+... padding: Union[bool, str, PaddingStrategy] = True
+... max_length: Optional[int] = None
+... pad_to_multiple_of: Optional[int] = None
+
+... def __call__(self, features):
+... label_name = "label" if "label" in features[0].keys() else "labels"
+... labels = [feature.pop(label_name) for feature in features]
+... batch_size = len(features)
+... num_choices = len(features[0]["input_ids"])
+... flattened_features = [
+... [{k: v[i] for k, v in feature.items()} for i in range(num_choices)] for feature in features
+... ]
+... flattened_features = sum(flattened_features, [])
+
+... batch = self.tokenizer.pad(
+... flattened_features,
+... padding=self.padding,
+... max_length=self.max_length,
+... pad_to_multiple_of=self.pad_to_multiple_of,
+... return_tensors="pt",
+... )
+
+... batch = {k: v.view(batch_size, num_choices, -1) for k, v in batch.items()}
+... batch["labels"] = torch.tensor(labels, dtype=torch.int64)
+... return batch
+```
+
+
+```py
+>>> from dataclasses import dataclass
+>>> from transformers.tokenization_utils_base import PreTrainedTokenizerBase, PaddingStrategy
+>>> from typing import Optional, Union
+>>> import tensorflow as tf
+
+
+>>> @dataclass
+... class DataCollatorForMultipleChoice:
+... """
+... Data collator that will dynamically pad the inputs for multiple choice received.
+... """
+
+... tokenizer: PreTrainedTokenizerBase
+... padding: Union[bool, str, PaddingStrategy] = True
+... max_length: Optional[int] = None
+... pad_to_multiple_of: Optional[int] = None
+
+... def __call__(self, features):
+... label_name = "label" if "label" in features[0].keys() else "labels"
+... labels = [feature.pop(label_name) for feature in features]
+... batch_size = len(features)
+... num_choices = len(features[0]["input_ids"])
+... flattened_features = [
+... [{k: v[i] for k, v in feature.items()} for i in range(num_choices)] for feature in features
+... ]
+... flattened_features = sum(flattened_features, [])
+
+... batch = self.tokenizer.pad(
+... flattened_features,
+... padding=self.padding,
+... max_length=self.max_length,
+... pad_to_multiple_of=self.pad_to_multiple_of,
+... return_tensors="tf",
+... )
+
+... batch = {k: tf.reshape(v, (batch_size, num_choices, -1)) for k, v in batch.items()}
+... batch["labels"] = tf.convert_to_tensor(labels, dtype=tf.int64)
+... return batch
+```
+
+
+
+## Evaluate
+
+トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) メトリクスを読み込みます (🤗 Evaluate [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照してください) ) メトリクスの読み込みと計算方法の詳細については、次を参照してください)。
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+次に、予測とラベルを [`~evaluate.EvaluationModule.compute`] に渡して精度を計算する関数を作成します。
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... predictions = np.argmax(predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=labels)
+```
+
+これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
+
+## Train
+
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[ここ](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForMultipleChoice`] を使用して BERT をロードします。
+
+```py
+>>> from transformers import AutoModelForMultipleChoice, TrainingArguments, Trainer
+
+>>> model = AutoModelForMultipleChoice.from_pretrained("google-bert/bert-base-uncased")
+```
+
+この時点で残っている手順は次の 3 つだけです。
+
+1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`Trainer`] は精度を評価し、トレーニング チェックポイントを保存します。
+2. トレーニング引数を、モデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Trainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_swag_model",
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... load_best_model_at_end=True,
+... learning_rate=5e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_swag["train"],
+... eval_dataset=tokenized_swag["validation"],
+... processing_class=tokenizer,
+... data_collator=DataCollatorForMultipleChoice(tokenizer=tokenizer),
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できますように。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-a-tensorflow-model-with-keras) の基本的なチュートリアルをご覧ください。
+
+
+TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_train_epochs = 2
+>>> total_train_steps = (len(tokenized_swag["train"]) // batch_size) * num_train_epochs
+>>> optimizer, schedule = create_optimizer(init_lr=5e-5, num_warmup_steps=0, num_train_steps=total_train_steps)
+```
+
+次に、[`TFAutoModelForMultipleChoice`] を使用して BERT をロードできます。
+
+```py
+>>> from transformers import TFAutoModelForMultipleChoice
+
+>>> model = TFAutoModelForMultipleChoice.from_pretrained("google-bert/bert-base-uncased")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
+
+```py
+>>> data_collator = DataCollatorForMultipleChoice(tokenizer=tokenizer)
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_swag["train"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_swag["validation"],
+... shuffle=False,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
+
+```py
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+トレーニングを開始する前にセットアップする最後の 2 つのことは、予測から精度を計算することと、モデルをハブにプッシュする方法を提供することです。どちらも [Keras コールバック](../main_classes/keras_callbacks) を使用して行われます。
+
+`compute_metrics` 関数を [`~transformers.KerasMetricCallback`] に渡します。
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+[`~transformers.PushToHubCallback`] でモデルとトークナイザーをプッシュする場所を指定します。
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_model",
+... tokenizer=tokenizer,
+... )
+```
+
+次に、コールバックをまとめてバンドルします。
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=2, callbacks=callbacks)
+```
+
+トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
+
+
+
+
+
+
+
+複数選択用にモデルを微調整する方法の詳細な例については、対応するセクションを参照してください。
+[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice.ipynb)
+または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice-tf.ipynb)。
+
+
+
+
+# Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+いくつかのテキストと 2 つの回答候補を考えてください。
+
+```py
+>>> prompt = "France has a bread law, Le Décret Pain, with strict rules on what is allowed in a traditional baguette."
+>>> candidate1 = "The law does not apply to croissants and brioche."
+>>> candidate2 = "The law applies to baguettes."
+```
+
+
+
+
+各プロンプトと回答候補のペアをトークン化し、PyTorch テンソルを返します。いくつかの`lables`も作成する必要があります。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_swag_model")
+>>> inputs = tokenizer([[prompt, candidate1], [prompt, candidate2]], return_tensors="pt", padding=True)
+>>> labels = torch.tensor(0).unsqueeze(0)
+```
+
+入力とラベルをモデルに渡し、`logits`を返します。
+
+```py
+>>> from transformers import AutoModelForMultipleChoice
+
+>>> model = AutoModelForMultipleChoice.from_pretrained("my_awesome_swag_model")
+>>> outputs = model(**{k: v.unsqueeze(0) for k, v in inputs.items()}, labels=labels)
+>>> logits = outputs.logits
+```
+
+最も高い確率でクラスを取得します。
+
+```py
+>>> predicted_class = logits.argmax().item()
+>>> predicted_class
+'0'
+```
+
+
+
+各プロンプトと回答候補のペアをトークン化し、TensorFlow テンソルを返します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_swag_model")
+>>> inputs = tokenizer([[prompt, candidate1], [prompt, candidate2]], return_tensors="tf", padding=True)
+```
+
+入力をモデルに渡し、`logits`を返します。
+
+```py
+>>> from transformers import TFAutoModelForMultipleChoice
+
+>>> model = TFAutoModelForMultipleChoice.from_pretrained("my_awesome_swag_model")
+>>> inputs = {k: tf.expand_dims(v, 0) for k, v in inputs.items()}
+>>> outputs = model(inputs)
+>>> logits = outputs.logits
+```
+
+最も高い確率でクラスを取得します。
+
+```py
+>>> predicted_class = int(tf.math.argmax(logits, axis=-1)[0])
+>>> predicted_class
+'0'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/object_detection.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/object_detection.md
new file mode 100644
index 0000000000000000000000000000000000000000..31e8effa54b224deb50a1fbc06e90f2ce972e5b4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/object_detection.md
@@ -0,0 +1,598 @@
+
+
+# Object detection
+
+[[open-in-colab]]
+
+オブジェクト検出は、画像内のインスタンス (人間、建物、車など) を検出するコンピューター ビジョン タスクです。物体検出モデルは画像を入力および出力として受け取ります
+検出されたオブジェクトの境界ボックスと関連するラベルの座標。画像には複数のオブジェクトを含めることができます。
+それぞれに独自の境界ボックスとラベルがあり (例: 車と建物を持つことができます)、各オブジェクトは
+画像のさまざまな部分に存在する必要があります (たとえば、画像には複数の車が含まれている可能性があります)。
+このタスクは、歩行者、道路標識、信号機などを検出するために自動運転で一般的に使用されます。
+他のアプリケーションには、画像内のオブジェクトのカウント、画像検索などが含まれます。
+
+このガイドでは、次の方法を学習します。
+
+ 1. Finetune [DETR](https://huggingface.co/docs/transformers/model_doc/detr)、畳み込みアルゴリズムを組み合わせたモデル
+ [CPPE-5](https://huggingface.co/datasets/cppe-5) 上のエンコーダー/デコーダー トランスフォーマーを備えたバックボーン
+ データセット。
+ 2. 微調整したモデルを推論に使用します。
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/object-detection) を確認することをお勧めします。
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+
+```bash
+pip install -q datasets transformers evaluate timm albumentations
+```
+
+🤗 データセットを使用して Hugging Face Hub からデータセットをロードし、🤗 トランスフォーマーを使用してモデルをトレーニングします。
+データを増強するための`albumentations`。 `timm` は現在、DETR モデルの畳み込みバックボーンをロードするために必要です。
+
+モデルをコミュニティと共有することをお勧めします。 Hugging Face アカウントにログインして、ハブにアップロードします。
+プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load the CPPE-5 dataset
+
+[CPPE-5 データセット](https://huggingface.co/datasets/cppe-5) には、次の画像が含まれています。
+新型コロナウイルス感染症のパンデミックにおける医療用個人保護具 (PPE) を識別する注釈。
+
+データセットをロードすることから始めます。
+
+```py
+>>> from datasets import load_dataset
+
+>>> cppe5 = load_dataset("cppe-5")
+>>> cppe5
+DatasetDict({
+ train: Dataset({
+ features: ['image_id', 'image', 'width', 'height', 'objects'],
+ num_rows: 1000
+ })
+ test: Dataset({
+ features: ['image_id', 'image', 'width', 'height', 'objects'],
+ num_rows: 29
+ })
+})
+```
+
+このデータセットには、1000 枚の画像を含むトレーニング セットと 29 枚の画像を含むテスト セットがすでに付属していることがわかります。
+
+データに慣れるために、例がどのようなものかを調べてください。
+
+```py
+>>> cppe5["train"][0]
+{'image_id': 15,
+ 'image': ,
+ 'width': 943,
+ 'height': 663,
+ 'objects': {'id': [114, 115, 116, 117],
+ 'area': [3796, 1596, 152768, 81002],
+ 'bbox': [[302.0, 109.0, 73.0, 52.0],
+ [810.0, 100.0, 57.0, 28.0],
+ [160.0, 31.0, 248.0, 616.0],
+ [741.0, 68.0, 202.0, 401.0]],
+ 'category': [4, 4, 0, 0]}}
+```
+
+データセット内の例には次のフィールドがあります。
+- `image_id`: サンプルの画像ID
+- `image`: 画像を含む `PIL.Image.Image` オブジェクト
+- `width`: 画像の幅
+- `height`: 画像の高さ
+- `objects`: 画像内のオブジェクトの境界ボックスのメタデータを含む辞書:
+ - `id`: アノテーションID
+ - `area`: 境界ボックスの領域
+ - `bbox`: オブジェクトの境界ボックス ([COCO 形式](https://albumentations.ai/docs/getting_started/bounding_boxes_augmentation/#coco) )
+ - `category`: オブジェクトのカテゴリー。可能な値には、`Coverall (0)`、`Face_Shield (1)`、`Gloves (2)`、`Goggles (3)`、および `Mask (4)` が含まれます。
+
+`bbox`フィールドが COCO 形式に従っていることに気づくかもしれません。これは DETR モデルが予期する形式です。
+ただし、「オブジェクト」内のフィールドのグループ化は、DETR が必要とする注釈形式とは異なります。あなたはするであろう
+このデータをトレーニングに使用する前に、いくつかの前処理変換を適用する必要があります。
+
+データをさらに深く理解するには、データセット内の例を視覚化します。
+
+```py
+>>> import numpy as np
+>>> import os
+>>> from PIL import Image, ImageDraw
+
+>>> image = cppe5["train"][0]["image"]
+>>> annotations = cppe5["train"][0]["objects"]
+>>> draw = ImageDraw.Draw(image)
+
+>>> categories = cppe5["train"].features["objects"].feature["category"].names
+
+>>> id2label = {index: x for index, x in enumerate(categories, start=0)}
+>>> label2id = {v: k for k, v in id2label.items()}
+
+>>> for i in range(len(annotations["id"])):
+... box = annotations["bbox"][i]
+... class_idx = annotations["category"][i]
+... x, y, w, h = tuple(box)
+... draw.rectangle((x, y, x + w, y + h), outline="red", width=1)
+... draw.text((x, y), id2label[class_idx], fill="white")
+
+>>> image
+```
+
+
+
+
COCO スタイルの指標 を使用して評価されます。
+既存のメトリクス実装のいずれかを使用できますが、ここでは`torchvision`のメトリクス実装を使用して最終的なメトリクスを評価します。
+ハブにプッシュしたモデル。
+
+`torchvision`エバリュエーターを使用するには、グラウンド トゥルース COCO データセットを準備する必要があります。 COCO データセットを構築するための API
+データを特定の形式で保存する必要があるため、最初に画像と注釈をディスクに保存する必要があります。と同じように
+トレーニング用にデータを準備するとき、`cppe5["test"]` からの注釈をフォーマットする必要があります。ただし、画像
+そのままでいるべきです。
+
+評価ステップには少し作業が必要ですが、大きく 3 つのステップに分けることができます。
+まず、`cppe5["test"]` セットを準備します。注釈をフォーマットし、データをディスクに保存します。
+
+
+```py
+>>> import json
+
+
+>>> # format annotations the same as for training, no need for data augmentation
+>>> def val_formatted_anns(image_id, objects):
+... annotations = []
+... for i in range(0, len(objects["id"])):
+... new_ann = {
+... "id": objects["id"][i],
+... "category_id": objects["category"][i],
+... "iscrowd": 0,
+... "image_id": image_id,
+... "area": objects["area"][i],
+... "bbox": objects["bbox"][i],
+... }
+... annotations.append(new_ann)
+
+... return annotations
+
+
+>>> # Save images and annotations into the files torchvision.datasets.CocoDetection expects
+>>> def save_cppe5_annotation_file_images(cppe5):
+... output_json = {}
+... path_output_cppe5 = f"{os.getcwd()}/cppe5/"
+
+... if not os.path.exists(path_output_cppe5):
+... os.makedirs(path_output_cppe5)
+
+... path_anno = os.path.join(path_output_cppe5, "cppe5_ann.json")
+... categories_json = [{"supercategory": "none", "id": id, "name": id2label[id]} for id in id2label]
+... output_json["images"] = []
+... output_json["annotations"] = []
+... for example in cppe5:
+... ann = val_formatted_anns(example["image_id"], example["objects"])
+... output_json["images"].append(
+... {
+... "id": example["image_id"],
+... "width": example["image"].width,
+... "height": example["image"].height,
+... "file_name": f"{example['image_id']}.png",
+... }
+... )
+... output_json["annotations"].extend(ann)
+... output_json["categories"] = categories_json
+
+... with open(path_anno, "w") as file:
+... json.dump(output_json, file, ensure_ascii=False, indent=4)
+
+... for im, img_id in zip(cppe5["image"], cppe5["image_id"]):
+... path_img = os.path.join(path_output_cppe5, f"{img_id}.png")
+... im.save(path_img)
+
+... return path_output_cppe5, path_anno
+```
+
+次に、`cocoevaluator`で利用できる`CocoDetection`クラスのインスタンスを用意します。
+
+
+```py
+>>> import torchvision
+
+
+>>> class CocoDetection(torchvision.datasets.CocoDetection):
+... def __init__(self, img_folder, image_processor, ann_file):
+... super().__init__(img_folder, ann_file)
+... self.image_processor = image_processor
+
+... def __getitem__(self, idx):
+... # read in PIL image and target in COCO format
+... img, target = super(CocoDetection, self).__getitem__(idx)
+
+... # preprocess image and target: converting target to DETR format,
+... # resizing + normalization of both image and target)
+... image_id = self.ids[idx]
+... target = {"image_id": image_id, "annotations": target}
+... encoding = self.image_processor(images=img, annotations=target, return_tensors="pt")
+... pixel_values = encoding["pixel_values"].squeeze() # remove batch dimension
+... target = encoding["labels"][0] # remove batch dimension
+
+... return {"pixel_values": pixel_values, "labels": target}
+
+
+>>> im_processor = AutoImageProcessor.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
+
+>>> path_output_cppe5, path_anno = save_cppe5_annotation_file_images(cppe5["test"])
+>>> test_ds_coco_format = CocoDetection(path_output_cppe5, im_processor, path_anno)
+```
+
+最後に、メトリクスをロードして評価を実行します。
+
+```py
+>>> import evaluate
+>>> from tqdm import tqdm
+
+>>> model = AutoModelForObjectDetection.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
+>>> module = evaluate.load("ybelkada/cocoevaluate", coco=test_ds_coco_format.coco)
+>>> val_dataloader = torch.utils.data.DataLoader(
+... test_ds_coco_format, batch_size=8, shuffle=False, num_workers=4, collate_fn=collate_fn
+... )
+
+>>> with torch.no_grad():
+... for idx, batch in enumerate(tqdm(val_dataloader)):
+... pixel_values = batch["pixel_values"]
+... pixel_mask = batch["pixel_mask"]
+
+... labels = [
+... {k: v for k, v in t.items()} for t in batch["labels"]
+... ] # these are in DETR format, resized + normalized
+
+... # forward pass
+... outputs = model(pixel_values=pixel_values, pixel_mask=pixel_mask)
+
+... orig_target_sizes = torch.stack([target["orig_size"] for target in labels], dim=0)
+... results = im_processor.post_process(outputs, orig_target_sizes) # convert outputs of model to Pascal VOC format (xmin, ymin, xmax, ymax)
+
+... module.add(prediction=results, reference=labels)
+... del batch
+
+>>> results = module.compute()
+>>> print(results)
+Accumulating evaluation results...
+DONE (t=0.08s).
+IoU metric: bbox
+ Average Precision (AP) @[ IoU=0.50:0.95 | area= all | maxDets=100 ] = 0.352
+ Average Precision (AP) @[ IoU=0.50 | area= all | maxDets=100 ] = 0.681
+ Average Precision (AP) @[ IoU=0.75 | area= all | maxDets=100 ] = 0.292
+ Average Precision (AP) @[ IoU=0.50:0.95 | area= small | maxDets=100 ] = 0.168
+ Average Precision (AP) @[ IoU=0.50:0.95 | area=medium | maxDets=100 ] = 0.208
+ Average Precision (AP) @[ IoU=0.50:0.95 | area= large | maxDets=100 ] = 0.429
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= all | maxDets= 1 ] = 0.274
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= all | maxDets= 10 ] = 0.484
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= all | maxDets=100 ] = 0.501
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= small | maxDets=100 ] = 0.191
+ Average Recall (AR) @[ IoU=0.50:0.95 | area=medium | maxDets=100 ] = 0.323
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= large | maxDets=100 ] = 0.590
+```
+
+これらの結果は、[`~transformers.TrainingArguments`] のハイパーパラメータを調整することでさらに改善できます。試してごらん!
+
+## Inference
+
+DETR モデルを微調整して評価し、Hugging Face Hub にアップロードしたので、それを推論に使用できます。
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。パイプラインをインスタンス化する
+モデルを使用してオブジェクトを検出し、それに画像を渡します。
+
+
+```py
+>>> from transformers import pipeline
+>>> import requests
+
+>>> url = "https://i.imgur.com/2lnWoly.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> obj_detector = pipeline("object-detection", model="devonho/detr-resnet-50_finetuned_cppe5")
+>>> obj_detector(image)
+```
+
+必要に応じて、パイプラインの結果を手動で複製することもできます。
+
+```py
+>>> image_processor = AutoImageProcessor.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
+>>> model = AutoModelForObjectDetection.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
+
+>>> with torch.no_grad():
+... inputs = image_processor(images=image, return_tensors="pt")
+... outputs = model(**inputs)
+... target_sizes = torch.tensor([image.size[::-1]])
+... results = image_processor.post_process_object_detection(outputs, threshold=0.5, target_sizes=target_sizes)[0]
+
+>>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+... box = [round(i, 2) for i in box.tolist()]
+... print(
+... f"Detected {model.config.id2label[label.item()]} with confidence "
+... f"{round(score.item(), 3)} at location {box}"
+... )
+Detected Coverall with confidence 0.566 at location [1215.32, 147.38, 4401.81, 3227.08]
+Detected Mask with confidence 0.584 at location [2449.06, 823.19, 3256.43, 1413.9]
+```
+
+結果をプロットしてみましょう:
+
+```py
+>>> draw = ImageDraw.Draw(image)
+
+>>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+... box = [round(i, 2) for i in box.tolist()]
+... x, y, x2, y2 = tuple(box)
+... draw.rectangle((x, y, x2, y2), outline="red", width=1)
+... draw.text((x, y), model.config.id2label[label.item()], fill="white")
+
+>>> image
+```
+
+
+
+
+
+迅速なエンジニアリングは、LLM 出力最適化プロセスの一部にすぎません。もう 1 つの重要な要素は、
+最適なテキスト生成戦略。 LLM が生成時に後続の各トークンを選択する方法をカスタマイズできます。
+トレーニング可能なパラメータを一切変更せずにテキストを作成します。テキスト生成パラメータを微調整することで、
+生成されたテキストに繰り返しが含まれているため、より一貫性があり人間らしい響きになります。
+テキスト生成戦略とパラメーターはこのガイドの範囲外ですが、これらのトピックについて詳しくは、次のトピックを参照してください。
+次のガイド:
+
+* [LLM による生成](../llm_tutorial)
+* [テキスト生成戦略](../generation_strategies)
+
+
+
+## Basics of prompting
+
+### Types of models
+
+最新の LLM の大部分は、デコーダ専用のトランスフォーマーです。例としては、[LLaMA](../model_doc/llama)、
+[Llama2](../model_doc/llama2)、[Falcon](../model_doc/falcon)、[GPT2](../model_doc/gpt2)。ただし、遭遇する可能性があります
+エンコーダ デコーダ トランスフォーマ LLM も同様です。たとえば、[Flan-T5](../model_doc/flan-t5) や [BART](../model_doc/bart) です。
+
+エンコーダ デコーダ スタイルのモデルは通常、出力が入力に**大きく**依存する生成タスクで使用されます。
+たとえば、翻訳と要約です。デコーダ専用モデルは、他のすべてのタイプの生成タスクに使用されます。
+
+パイプラインを使用して LLM でテキストを生成する場合、使用している LLM のタイプを知ることが重要です。
+異なるパイプラインを使用します。
+
+`text-generation`パイプラインを使用してデコーダのみのモデルで推論を実行します。
+
+```python
+>>> from transformers import pipeline
+>>> import torch
+
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+
+>>> generator = pipeline('text-generation', model = 'openai-community/gpt2')
+>>> prompt = "Hello, I'm a language model"
+
+>>> generator(prompt, max_length = 30)
+[{'generated_text': "Hello, I'm a language model expert, so I'm a big believer in the concept that I know very well and then I try to look into"}]
+```
+
+エンコーダー/デコーダーを使用して推論を実行するには、`text2text-generation` パイプラインを使用します。
+
+```python
+>>> text2text_generator = pipeline("text2text-generation", model = 'google/flan-t5-base')
+>>> prompt = "Translate from English to French: I'm very happy to see you"
+
+>>> text2text_generator(prompt)
+[{'generated_text': 'Je suis très heureuse de vous rencontrer.'}]
+```
+
+### Base vs instruct/chat models
+
+🤗 Hub で利用できる最近の LLM チェックポイントのほとんどには、base と instruct (または chat) の 2 つのバージョンがあります。例えば、
+[`tiiuae/falcon-7b`](https://huggingface.co/tiiuae/falcon-7b) および [`tiiuae/falcon-7b-instruct`](https://huggingface.co/tiiuae/falcon-7b) -指示する)。
+
+基本モデルは、最初のプロンプトが与えられたときにテキストを完成させるのには優れていますが、NLP タスクには理想的ではありません。
+指示に従う必要がある場合、または会話で使用する場合に使用します。ここで、指示 (チャット) バージョンが登場します。
+これらのチェックポイントは、命令と会話データに基づいて事前トレーニングされたベース バージョンをさらに微調整した結果です。
+この追加の微調整により、多くの NLP タスクにとってより適切な選択肢になります。
+
+[`tiiuae/falcon-7b-instruct`](https://huggingface.co/tiiuae/falcon-7b-instruct) で使用できるいくつかの簡単なプロンプトを示してみましょう。
+いくつかの一般的な NLP タスクを解決します。
+
+### NLP tasks
+
+まず、環境をセットアップしましょう。
+
+```bash
+pip install -q transformers accelerate
+```
+
+次に、適切なパイプライン (`text_generation`) を使用してモデルをロードしましょう。
+
+```python
+>>> from transformers import pipeline, AutoTokenizer
+>>> import torch
+
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+>>> model = "tiiuae/falcon-7b-instruct"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(model)
+>>> pipe = pipeline(
+... "text-generation",
+... model=model,
+... tokenizer=tokenizer,
+... torch_dtype=torch.bfloat16,
+... device_map="auto",
+... )
+```
+
+
+
+Falcon モデルは `bfloat16` データ型を使用してトレーニングされたため、同じものを使用することをお勧めします。これには、最近の
+CUDA のバージョンに準拠しており、最新のカードで最適に動作します。
+
+
+
+パイプライン経由でモデルをロードしたので、プロンプトを使用して NLP タスクを解決する方法を見てみましょう。
+
+#### Text classification
+
+テキスト分類の最も一般的な形式の 1 つはセンチメント分析であり、「ポジティブ」、「ネガティブ」、「ネガティブ」などのラベルを割り当てます。
+または、一連のテキストに対して「中立」です。与えられたテキスト (映画レビュー) を分類するようにモデルに指示するプロンプトを作成してみましょう。
+まず指示を与え、次に分類するテキストを指定します。そのままにしておくのではなく、
+応答の先頭にも追加します - `"Sentiment: "`:
+
+```python
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+>>> prompt = """Classify the text into neutral, negative or positive.
+... Text: This movie is definitely one of my favorite movies of its kind. The interaction between respectable and morally strong characters is an ode to chivalry and the honor code amongst thieves and policemen.
+... Sentiment:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=10,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result: Classify the text into neutral, negative or positive.
+Text: This movie is definitely one of my favorite movies of its kind. The interaction between respectable and morally strong characters is an ode to chivalry and the honor code amongst thieves and policemen.
+Sentiment:
+Positive
+```
+
+その結果、出力には、手順で提供したリストの分類ラベルが含まれており、それは正しいラベルです。
+
+
+
+プロンプトに加えて、`max_new_tokens`パラメータを渡していることに気づくかもしれません。トークンの数を制御します。
+モデルが生成します。これは、学習できる多くのテキスト生成パラメーターの 1 つです。
+[テキスト生成戦略](../generation_strategies) ガイドを参照してください。
+
+
+
+#### Named Entity Recognition
+
+固有表現認識 (NER) は、テキスト内の人物、場所、組織などの固有表現を検索するタスクです。
+プロンプトの指示を変更して、LLM にこのタスクを実行させましょう。ここでは`return_full_text = False`も設定しましょう
+出力にプロンプトが含まれないようにします。
+
+```python
+>>> torch.manual_seed(1) # doctest: +IGNORE_RESULT
+>>> prompt = """Return a list of named entities in the text.
+... Text: The Golden State Warriors are an American professional basketball team based in San Francisco.
+... Named entities:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=15,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"{seq['generated_text']}")
+- Golden State Warriors
+- San Francisco
+```
+
+ご覧のとおり、モデルは指定されたテキストから 2 つの名前付きエンティティを正しく識別しました。
+
+#### Translation
+
+LLM が実行できるもう 1 つのタスクは翻訳です。このタスクにはエンコーダー/デコーダー モデルを使用することを選択できますが、ここでは
+例を簡単にするために、きちんとした仕事をする Falcon-7b-instruct を使い続けます。もう一度、方法は次のとおりです
+テキストの一部を英語からイタリア語に翻訳するようにモデルに指示する基本的なプロンプトを作成できます。
+
+```python
+>>> torch.manual_seed(2) # doctest: +IGNORE_RESULT
+>>> prompt = """Translate the English text to Italian.
+... Text: Sometimes, I've believed as many as six impossible things before breakfast.
+... Translation:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=20,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"{seq['generated_text']}")
+A volte, ho creduto a sei impossibili cose prima di colazione.
+```
+
+ここでは、出力生成時にモデルがもう少し柔軟になるように `do_sample=True` と `top_k=10` を追加しました。
+
+#### Text summarization
+
+翻訳と同様に、テキストの要約も、出力が入力に**大きく**依存する生成タスクです。
+エンコーダ/デコーダ モデルの方が良い選択になる可能性があります。ただし、デコーダ スタイルのモデルもこのタスクに使用できます。
+以前は、プロンプトの先頭に指示を配置していました。ただし、プロンプトの最後で、
+指示を与えるのに適した場所でもあります。通常、命令はどちらかの端に配置することをお勧めします。
+
+```python
+>>> torch.manual_seed(3) # doctest: +IGNORE_RESULT
+>>> prompt = """Permaculture is a design process mimicking the diversity, functionality and resilience of natural ecosystems. The principles and practices are drawn from traditional ecological knowledge of indigenous cultures combined with modern scientific understanding and technological innovations. Permaculture design provides a framework helping individuals and communities develop innovative, creative and effective strategies for meeting basic needs while preparing for and mitigating the projected impacts of climate change.
+... Write a summary of the above text.
+... Summary:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=30,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"{seq['generated_text']}")
+Permaculture is an ecological design mimicking natural ecosystems to meet basic needs and prepare for climate change. It is based on traditional knowledge and scientific understanding.
+```
+
+#### Question answering
+
+質問応答タスクの場合、プロンプトを次の論理コンポーネントに構造化できます: 指示、コンテキスト、質問、
+先頭の単語またはフレーズ (`"Answer:"`) を使用して、モデルを操作して答えの生成を開始します。
+
+
+```python
+>>> torch.manual_seed(4) # doctest: +IGNORE_RESULT
+>>> prompt = """Answer the question using the context below.
+... Context: Gazpacho is a cold soup and drink made of raw, blended vegetables. Most gazpacho includes stale bread, tomato, cucumbers, onion, bell peppers, garlic, olive oil, wine vinegar, water, and salt. Northern recipes often include cumin and/or pimentón (smoked sweet paprika). Traditionally, gazpacho was made by pounding the vegetables in a mortar with a pestle; this more laborious method is still sometimes used as it helps keep the gazpacho cool and avoids the foam and silky consistency of smoothie versions made in blenders or food processors.
+... Question: What modern tool is used to make gazpacho?
+... Answer:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=10,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result: Modern tools are used, such as immersion blenders
+```
+
+#### Reasoning
+
+LLM にとって推論は最も困難なタスクの 1 つであり、良い結果を達成するには、多くの場合、次のような高度なプロンプト テクニックを適用する必要があります。
+[Chain-of-thought](#chain-of-thought)。
+
+基本的なプロンプトを使用して、単純な算術タスクに関するモデル推論を作成できるかどうか試してみましょう。
+
+```python
+>>> torch.manual_seed(5) # doctest: +IGNORE_RESULT
+>>> prompt = """There are 5 groups of students in the class. Each group has 4 students. How many students are there in the class?"""
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=30,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result:
+There are a total of 5 groups, so there are 5 x 4=20 students in the class.
+```
+
+正しい!もう少し複雑さを増やして、基本的なプロンプトで問題を解決できるかどうかを確認してみましょう。
+
+```python
+>>> torch.manual_seed(6) # doctest: +IGNORE_RESULT
+>>> prompt = """I baked 15 muffins. I ate 2 muffins and gave 5 muffins to a neighbor. My partner then bought 6 more muffins and ate 2. How many muffins do we now have?"""
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=10,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result:
+The total number of muffins now is 21
+```
+
+これは間違った答えです。12 である必要があります。この場合、プロンプトが基本的すぎるか、選択内容が原因である可能性があります。
+結局のところ、Falcon の最小バージョンを選択しました。あらゆるサイズのモデルでは推論が困難ですが、より大きなモデルでは
+モデルのパフォーマンスが向上する可能性があります。
+
+## Best practices of LLM prompting
+
+ガイドのこのセクションでは、プロンプトの結果を改善する傾向にあるベスト プラクティスのリストをまとめました。
+
+* 使用するモデルを選択する場合は、最新かつ最も機能的なモデルの方がパフォーマンスが向上する可能性があります。
+* シンプルで短いプロンプトから始めて、そこから繰り返します。
+* 指示はプロンプトの最初または最後に入力してください。大規模なコンテキストを扱う場合、モデルはさまざまな最適化を適用して、アテンションの複雑さが二次的に拡大するのを防ぎます。これにより、モデルはプロンプトの途中よりも最初または最後に注意を払うようになります。
+* 指示と、それが適用されるテキストを明確に区別してください。これについては、次のセクションで詳しく説明します。
+* タスクと望ましい結果 (その形式、長さ、スタイル、言語など) について具体的かつ説明的にします。
+* 曖昧な説明や指示は避けてください。
+*「何をしてはいけないか」という指示ではなく、「何をすべきか」という指示を優先します。
+* 最初の単語を書いて (またはモデルの最初の文を始めて)、出力を正しい方向に「導き」ます。
+* [Few-shot prompting](#few-shot-prompting) や [Chain-of-thought](#chain-of-thought) などの高度なテクニックを使用します。
+* さまざまなモデルでプロンプトをテストして、その堅牢性を評価します。
+* プロンプトのバージョンを確認し、パフォーマンスを追跡します。
+
+## Advanced prompting techniques
+
+### Few-shot prompting
+
+上記のセクションの基本的なプロンプトは、「ゼロショット」プロンプトの例です。つまり、モデルにはすでに与えられています。
+指示とコンテキストはありますが、解決策を含む例はありません。通常、命令データセットに基づいて微調整された LLM
+このような「ゼロショット」タスクでも優れたパフォーマンスを発揮します。ただし、タスクがより複雑であったり微妙な点があったりする場合があります。
+出力には、命令だけではモデルが理解できないいくつかの要件があります。この場合、次のことができます。
+少数ショット プロンプトと呼ばれるテクニックを試してください。
+
+少数ショット プロンプトでは、モデルにパフォーマンスを向上させるためのより多くのコンテキストを提供するプロンプト内の例が提供されます。
+例では、例のパターンに従って出力を生成するようにモデルを条件付けします。
+
+以下に例を示します。
+
+```python
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+>>> prompt = """Text: The first human went into space and orbited the Earth on April 12, 1961.
+... Date: 04/12/1961
+... Text: The first-ever televised presidential debate in the United States took place on September 28, 1960, between presidential candidates John F. Kennedy and Richard Nixon.
+... Date:"""
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=8,
+... do_sample=True,
+... top_k=10,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result: Text: The first human went into space and orbited the Earth on April 12, 1961.
+Date: 04/12/1961
+Text: The first-ever televised presidential debate in the United States took place on September 28, 1960, between presidential candidates John F. Kennedy and Richard Nixon.
+Date: 09/28/1960
+```
+
+上記のコード スニペットでは、モデルへの目的の出力を示すために 1 つの例を使用しました。したがって、これは、
+「ワンショット」プロンプト。ただし、タスクの複雑さに応じて、複数の例を使用する必要がある場合があります。
+
+数回のプロンプト手法の制限:
+- LLM は例のパターンを理解できますが、これらの手法は複雑な推論タスクではうまく機能しません。
+- 少数ショットのプロンプトでは、長いプロンプトを作成する必要があります。大量のトークンを含むプロンプトでは、計算量と待ち時間が増加する可能性があります。プロンプトの長さにも制限があります。
+- 多くの例を与えると、モデルが学習するつもりのなかったパターンを学習することがあります。 3番目の映画レビューはいつも否定的だということ。
+
+### Chain-of-thought
+
+思考連鎖 (CoT) プロンプトは、モデルを微調整して中間推論ステップを生成し、改善する手法です。
+複雑な推論タスクの結果。
+
+モデルを操作して推論ステップを生成するには、2 つの方法があります。
+- 質問に対する詳細な回答を含む例を示し、問題に対処する方法をモデルに示すことで、数回のプロンプトを表示します。
+- 「ステップごとに考えてみましょう」または「深呼吸して、問題をステップごとに解決してください」などのフレーズを追加してモデルに推論を指示します。
+
+[推論セクション](#reasoning) のマフィンの例に CoT テクニックを適用し、より大きなモデルを使用すると、
+[HuggingChat](https://huggingface.co/chat/)で遊べる(`tiiuae/falcon-180B-chat`)など、
+推論結果は大幅に改善されます。
+
+```text
+Let's go through this step-by-step:
+1. You start with 15 muffins.
+2. You eat 2 muffins, leaving you with 13 muffins.
+3. You give 5 muffins to your neighbor, leaving you with 8 muffins.
+4. Your partner buys 6 more muffins, bringing the total number of muffins to 14.
+5. Your partner eats 2 muffins, leaving you with 12 muffins.
+Therefore, you now have 12 muffins.
+```
+
+## Prompting vs fine-tuning
+
+プロンプトを最適化することで優れた結果を達成できますが、モデルを微調整するかどうかについてはまだ思案するかもしれません。
+あなたの場合にはもっとうまくいくでしょう。より小規模なモデルを微調整することが好ましいオプションである場合のいくつかのシナリオを次に示します。
+
+- ドメインが LLM が事前にトレーニングされたものと大きく異なっており、広範なプロンプト最適化では十分な結果が得られませんでした。
+- モデルが低リソース言語で適切に動作する必要があります。
+- 厳格な規制の下にある機密データでモデルをトレーニングする必要があります。
+- コスト、プライバシー、インフラストラクチャ、またはその他の制限により、小規模なモデルを使用する必要があります。
+
+上記のすべての例で、十分な大きさのファイルをすでに持っているか、簡単に入手できるかを確認する必要があります。
+ドメイン固有のデータセットを合理的なコストでモデルを微調整できます。十分な時間とリソースも必要になります
+モデルを微調整します。
+
+上記の例が当てはまらない場合は、プロンプトを最適化する方が有益であることがわかります。
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/question_answering.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/question_answering.md
new file mode 100644
index 0000000000000000000000000000000000000000..9217c211e6f973ddfe2d9ca6c3e3ad36bf6cf743
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/question_answering.md
@@ -0,0 +1,438 @@
+
+
+# Question answering
+
+[[open-in-colab]]
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/question-answering) を確認することをお勧めします。
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install transformers datasets evaluate
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load SQuAD dataset
+
+まず、🤗 データセット ライブラリから SQuAD データセットの小さいサブセットを読み込みます。これにより、完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
+
+
+```py
+>>> from datasets import load_dataset
+
+>>> squad = load_dataset("squad", split="train[:5000]")
+```
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train` 分割をトレイン セットとテスト セットに分割します。
+
+```py
+>>> squad = squad.train_test_split(test_size=0.2)
+```
+
+次に、例を見てみましょう。
+
+```py
+>>> squad["train"][0]
+{'answers': {'answer_start': [515], 'text': ['Saint Bernadette Soubirous']},
+ 'context': 'Architecturally, the school has a Catholic character. Atop the Main Building\'s gold dome is a golden statue of the Virgin Mary. Immediately in front of the Main Building and facing it, is a copper statue of Christ with arms upraised with the legend "Venite Ad Me Omnes". Next to the Main Building is the Basilica of the Sacred Heart. Immediately behind the basilica is the Grotto, a Marian place of prayer and reflection. It is a replica of the grotto at Lourdes, France where the Virgin Mary reputedly appeared to Saint Bernadette Soubirous in 1858. At the end of the main drive (and in a direct line that connects through 3 statues and the Gold Dome), is a simple, modern stone statue of Mary.',
+ 'id': '5733be284776f41900661182',
+ 'question': 'To whom did the Virgin Mary allegedly appear in 1858 in Lourdes France?',
+ 'title': 'University_of_Notre_Dame'
+}
+```
+
+ここにはいくつかの重要なフィールドがあります。
+
+- `answers`: 回答トークンと回答テキストの開始位置。
+- `context`: モデルが答えを抽出するために必要な背景情報。
+- `question`: モデルが答える必要がある質問。
+
+## Preprocess
+
+
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+```
+
+
+
+## Train
+
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[ここ](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForQuestionAnswering`] を使用して DitilBERT をロードします。
+
+```py
+>>> from transformers import AutoModelForQuestionAnswering, TrainingArguments, Trainer
+
+>>> model = AutoModelForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+この時点で残っている手順は次の 3 つだけです。
+
+1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。
+2. トレーニング引数をモデル、データセット、トークナイザー、データ照合器とともに [`Trainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_qa_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_squad["train"],
+... eval_dataset=tokenized_squad["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-a-tensorflow-model-with-keras) の基本的なチュートリアルをご覧ください。
+
+
+
+
+TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_epochs = 2
+>>> total_train_steps = (len(tokenized_squad["train"]) // batch_size) * num_epochs
+>>> optimizer, schedule = create_optimizer(
+... init_lr=2e-5,
+... num_warmup_steps=0,
+... num_train_steps=total_train_steps,
+... )
+```
+
+次に、[`TFAutoModelForQuestionAnswering`] を使用して DistilBERT をロードできます。
+
+```py
+>>> from transformers import TFAutoModelForQuestionAnswering
+
+>>> model = TFAutoModelForQuestionAnswering("distilbert/distilbert-base-uncased")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_squad["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_squad["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+トレーニングを開始する前に最後にセットアップすることは、モデルをハブにプッシュする方法を提供することです。これは、モデルとトークナイザーを [`~transformers.PushToHubCallback`] でプッシュする場所を指定することで実行できます。
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_qa_model",
+... tokenizer=tokenizer,
+... )
+```
+
+ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=[callback])
+```
+
+トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
+
+
+
+
+
+質問応答用のモデルを微調整する方法の詳細な例については、対応するドキュメントを参照してください。
+[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb)
+または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering-tf.ipynb)。
+
+
+
+## Evaluate
+
+質問応答の評価には、大量の後処理が必要です。時間がかかりすぎないように、このガイドでは評価ステップを省略しています。 [`Trainer`] はトレーニング中に評価損失を計算するため、モデルのパフォーマンスについて完全に分からないわけではありません。
+
+もっと時間があり、質問応答用のモデルを評価する方法に興味がある場合は、[質問応答](https://huggingface.co/course/chapter7/7?fw=pt#postprocessing) の章を参照してください。 🤗ハグフェイスコースから!
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+質問と、モデルに予測させたいコンテキストを考え出します。
+
+```py
+>>> question = "How many programming languages does BLOOM support?"
+>>> context = "BLOOM has 176 billion parameters and can generate text in 46 languages natural languages and 13 programming languages."
+```
+
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して質問応答用の`pipeline`をインスタンス化し、それにテキストを渡します。
+
+```py
+>>> from transformers import pipeline
+
+>>> question_answerer = pipeline("question-answering", model="my_awesome_qa_model")
+>>> question_answerer(question=question, context=context)
+{'score': 0.2058267742395401,
+ 'start': 10,
+ 'end': 95,
+ 'answer': '176 billion parameters and can generate text in 46 languages natural languages and 13'}
+```
+
+必要に応じて、`pipeline`の結果を手動で複製することもできます。
+
+
+
+
+テキストをトークン化して PyTorch テンソルを返します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_qa_model")
+>>> inputs = tokenizer(question, context, return_tensors="pt")
+```
+
+入力をモデルに渡し、`logits`を返します。
+
+
+```py
+>>> import torch
+>>> from transformers import AutoModelForQuestionAnswering
+
+>>> model = AutoModelForQuestionAnswering.from_pretrained("my_awesome_qa_model")
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+```
+
+モデル出力から開始位置と終了位置の最も高い確率を取得します。
+
+```py
+>>> answer_start_index = outputs.start_logits.argmax()
+>>> answer_end_index = outputs.end_logits.argmax()
+```
+
+予測されたトークンをデコードして答えを取得します。
+
+```py
+>>> predict_answer_tokens = inputs.input_ids[0, answer_start_index : answer_end_index + 1]
+>>> tokenizer.decode(predict_answer_tokens)
+'176 billion parameters and can generate text in 46 languages natural languages and 13'
+```
+
+
+
+テキストをトークン化し、TensorFlow テンソルを返します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_qa_model")
+>>> inputs = tokenizer(question, text, return_tensors="tf")
+```
+
+入力をモデルに渡し、`logits`を返します。
+
+
+```py
+>>> from transformers import TFAutoModelForQuestionAnswering
+
+>>> model = TFAutoModelForQuestionAnswering.from_pretrained("my_awesome_qa_model")
+>>> outputs = model(**inputs)
+```
+
+モデル出力から開始位置と終了位置の最も高い確率を取得します。
+
+```py
+>>> answer_start_index = int(tf.math.argmax(outputs.start_logits, axis=-1)[0])
+>>> answer_end_index = int(tf.math.argmax(outputs.end_logits, axis=-1)[0])
+```
+
+予測されたトークンをデコードして答えを取得します。
+
+```py
+>>> predict_answer_tokens = inputs.input_ids[0, answer_start_index : answer_end_index + 1]
+>>> tokenizer.decode(predict_answer_tokens)
+'176 billion parameters and can generate text in 46 languages natural languages and 13'
+```
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/semantic_segmentation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/semantic_segmentation.md
new file mode 100644
index 0000000000000000000000000000000000000000..cfbfd7b81c0193acc0db6c261d4425f48897d4e1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/semantic_segmentation.md
@@ -0,0 +1,600 @@
+
+
+# Semantic segmentation
+
+[[open-in-colab]]
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/image-segmentation) を確認することをお勧めします。
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install -q datasets transformers evaluate
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load SceneParse150 dataset
+
+まず、SceneParse150 データセットの小さいサブセットを 🤗 データセット ライブラリから読み込みます。これにより、完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
+
+```py
+>>> from datasets import load_dataset
+
+>>> ds = load_dataset("scene_parse_150", split="train[:50]")
+```
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train` 分割をトレイン セットとテスト セットに分割します。
+
+
+```py
+>>> ds = ds.train_test_split(test_size=0.2)
+>>> train_ds = ds["train"]
+>>> test_ds = ds["test"]
+```
+
+次に、例を見てみましょう。
+
+```py
+>>> train_ds[0]
+{'image': ,
+ 'annotation': ,
+ 'scene_category': 368}
+```
+
+- `image`: シーンの PIL イメージ。
+- `annotation`: セグメンテーション マップの PIL イメージ。モデルのターゲットでもあります。
+- `scene_category`: "kitchen"や"office"などの画像シーンを説明するカテゴリ ID。このガイドでは、`image`と`annotation`のみが必要になります。どちらも PIL イメージです。
+
+また、ラベル ID をラベル クラスにマップする辞書を作成することもできます。これは、後でモデルを設定するときに役立ちます。ハブからマッピングをダウンロードし、`id2label` および `label2id` ディクショナリを作成します。
+
+```py
+>>> import json
+>>> from pathlib import Path
+>>> from huggingface_hub import hf_hub_download
+
+>>> repo_id = "huggingface/label-files"
+>>> filename = "ade20k-id2label.json"
+>>> id2label = json.loads(Path(hf_hub_download(repo_id, filename, repo_type="dataset")).read_text())
+>>> id2label = {int(k): v for k, v in id2label.items()}
+>>> label2id = {v: k for k, v in id2label.items()}
+>>> num_labels = len(id2label)
+```
+
+## Preprocess
+
+次のステップでは、SegFormer 画像プロセッサをロードして、モデルの画像と注釈を準備します。このデータセットのような一部のデータセットは、バックグラウンド クラスとしてゼロインデックスを使用します。ただし、実際には背景クラスは 150 個のクラスに含まれていないため、`do_reduce_labels=True`を設定してすべてのラベルから 1 つを引く必要があります。ゼロインデックスは `255` に置き換えられるため、SegFormer の損失関数によって無視されます。
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> checkpoint = "nvidia/mit-b0"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint, do_reduce_labels=True)
+```
+
+
+
+
+モデルを過学習に対してより堅牢にするために、画像データセットにいくつかのデータ拡張を適用するのが一般的です。このガイドでは、[torchvision](https://pytorch.org/vision/stable/index.html) の [`ColorJitter`](https://pytorch.org/vision/stable/generated/torchvision.transforms.ColorJitter.html) 関数を使用します。 ) を使用して画像の色のプロパティをランダムに変更しますが、任意の画像ライブラリを使用することもできます。
+
+```py
+>>> from torchvision.transforms import ColorJitter
+
+>>> jitter = ColorJitter(brightness=0.25, contrast=0.25, saturation=0.25, hue=0.1)
+```
+
+次に、モデルの画像と注釈を準備するための 2 つの前処理関数を作成します。これらの関数は、画像を`pixel_values`に変換し、注釈を`labels`に変換します。トレーニング セットの場合、画像を画像プロセッサに提供する前に `jitter` が適用されます。テスト セットの場合、テスト中にデータ拡張が適用されないため、画像プロセッサは`images`を切り取って正規化し、`ラベル`のみを切り取ります。
+
+```py
+>>> def train_transforms(example_batch):
+... images = [jitter(x) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+
+
+>>> def val_transforms(example_batch):
+... images = [x for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+```
+
+データセット全体に`jitter`を適用するには、🤗 Datasets [`~datasets.Dataset.set_transform`] 関数を使用します。変換はオンザフライで適用されるため、高速で消費するディスク容量が少なくなります。
+
+```py
+>>> train_ds.set_transform(train_transforms)
+>>> test_ds.set_transform(val_transforms)
+```
+
+
+
+
+
+
+
+モデルを過学習に対してより堅牢にするために、画像データセットにいくつかのデータ拡張を適用するのが一般的です。
+このガイドでは、[`tf.image`](https://www.tensorflow.org/api_docs/python/tf/image) を使用して画像の色のプロパティをランダムに変更しますが、任意のプロパティを使用することもできます。画像
+好きな図書館。
+2 つの別々の変換関数を定義します。
+- 画像拡張を含むトレーニング データ変換
+- 🤗 Transformers のコンピューター ビジョン モデルはチャネル優先のレイアウトを想定しているため、画像を転置するだけの検証データ変換
+
+```py
+>>> import tensorflow as tf
+
+
+>>> def aug_transforms(image):
+... image = tf.keras.utils.img_to_array(image)
+... image = tf.image.random_brightness(image, 0.25)
+... image = tf.image.random_contrast(image, 0.5, 2.0)
+... image = tf.image.random_saturation(image, 0.75, 1.25)
+... image = tf.image.random_hue(image, 0.1)
+... image = tf.transpose(image, (2, 0, 1))
+... return image
+
+
+>>> def transforms(image):
+... image = tf.keras.utils.img_to_array(image)
+... image = tf.transpose(image, (2, 0, 1))
+... return image
+```
+
+次に、モデルの画像と注釈のバッチを準備する 2 つの前処理関数を作成します。これらの機能が適用されます
+画像変換を行い、以前にロードされた `image_processor` を使用して画像を `pixel_values` に変換し、
+`labels`への注釈。 `ImageProcessor` は、画像のサイズ変更と正規化も処理します。
+
+```py
+>>> def train_transforms(example_batch):
+... images = [aug_transforms(x.convert("RGB")) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+
+
+>>> def val_transforms(example_batch):
+... images = [transforms(x.convert("RGB")) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+```
+
+データセット全体に前処理変換を適用するには、🤗 Datasets [`~datasets.Dataset.set_transform`] 関数を使用します。
+変換はオンザフライで適用されるため、高速で消費するディスク容量が少なくなります。
+
+```py
+>>> train_ds.set_transform(train_transforms)
+>>> test_ds.set_transform(val_transforms)
+```
+
+
+
+## Evaluate
+
+トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[Mean Intersection over Union](https://huggingface.co/spaces/evaluate-metric/accuracy) (IoU) メトリックをロードします (🤗 Evaluate [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照して、メトリクスをロードして計算する方法の詳細を確認してください)。
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("mean_iou")
+```
+
+次に、メトリクスを [`~evaluate.EvaluationModule.compute`] する関数を作成します。予測を次のように変換する必要があります
+最初にロジットを作成し、次に [`~evaluate.EvaluationModule.compute`] を呼び出す前にラベルのサイズに一致するように再形成します。
+
+
+
+
+```py
+>>> import numpy as np
+>>> import torch
+>>> from torch import nn
+
+>>> def compute_metrics(eval_pred):
+... with torch.no_grad():
+... logits, labels = eval_pred
+... logits_tensor = torch.from_numpy(logits)
+... logits_tensor = nn.functional.interpolate(
+... logits_tensor,
+... size=labels.shape[-2:],
+... mode="bilinear",
+... align_corners=False,
+... ).argmax(dim=1)
+
+... pred_labels = logits_tensor.detach().cpu().numpy()
+... metrics = metric.compute(
+... predictions=pred_labels,
+... references=labels,
+... num_labels=num_labels,
+... ignore_index=255,
+... reduce_labels=False,
+... )
+... for key, value in metrics.items():
+... if type(value) is np.ndarray:
+... metrics[key] = value.tolist()
+... return metrics
+```
+
+
+
+
+
+
+
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... logits = tf.transpose(logits, perm=[0, 2, 3, 1])
+... logits_resized = tf.image.resize(
+... logits,
+... size=tf.shape(labels)[1:],
+... method="bilinear",
+... )
+
+... pred_labels = tf.argmax(logits_resized, axis=-1)
+... metrics = metric.compute(
+... predictions=pred_labels,
+... references=labels,
+... num_labels=num_labels,
+... ignore_index=-1,
+... reduce_labels=image_processor.do_reduce_labels,
+... )
+
+... per_category_accuracy = metrics.pop("per_category_accuracy").tolist()
+... per_category_iou = metrics.pop("per_category_iou").tolist()
+
+... metrics.update({f"accuracy_{id2label[i]}": v for i, v in enumerate(per_category_accuracy)})
+... metrics.update({f"iou_{id2label[i]}": v for i, v in enumerate(per_category_iou)})
+... return {"val_" + k: v for k, v in metrics.items()}
+```
+
+
+
+
+これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
+
+## Train
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[ここ](../training#finetune-with-trainer) の基本的なチュートリアルをご覧ください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForSemanticSegmentation`] を使用して SegFormer をロードし、ラベル ID とラベル クラス間のマッピングをモデルに渡します。
+
+```py
+>>> from transformers import AutoModelForSemanticSegmentation, TrainingArguments, Trainer
+
+>>> model = AutoModelForSemanticSegmentation.from_pretrained(checkpoint, id2label=id2label, label2id=label2id)
+```
+
+この時点で残っている手順は次の 3 つだけです。
+
+1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。 `image` 列が削除されるため、未使用の列を削除しないことが重要です。 `image` 列がないと、`pixel_values` を作成できません。この動作を防ぐには、`remove_unused_columns=False`を設定してください。他に必要なパラメータは、モデルの保存場所を指定する `output_dir` だけです。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`Trainer`] は IoU メトリックを評価し、トレーニング チェックポイントを保存します。
+2. トレーニング引数を、モデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Trainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="segformer-b0-scene-parse-150",
+... learning_rate=6e-5,
+... num_train_epochs=50,
+... per_device_train_batch_size=2,
+... per_device_eval_batch_size=2,
+... save_total_limit=3,
+... eval_strategy="steps",
+... save_strategy="steps",
+... save_steps=20,
+... eval_steps=20,
+... logging_steps=1,
+... eval_accumulation_steps=5,
+... remove_unused_columns=False,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=train_ds,
+... eval_dataset=test_ds,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+
+
+Keras を使用したモデルの微調整に慣れていない場合は、まず [基本チュートリアル](./training#train-a-tensorflow-model-with-keras) を確認してください。
+
+
+
+TensorFlow でモデルを微調整するには、次の手順に従います。
+1. トレーニングのハイパーパラメータを定義し、オプティマイザーと学習率スケジュールを設定します。
+2. 事前トレーニングされたモデルをインスタンス化します。
+3. 🤗 データセットを `tf.data.Dataset` に変換します。
+4. モデルをコンパイルします。
+5. コールバックを追加してメトリクスを計算し、モデルを 🤗 Hub にアップロードします
+6. `fit()` メソッドを使用してトレーニングを実行します。
+
+まず、ハイパーパラメーター、オプティマイザー、学習率スケジュールを定義します。
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 2
+>>> num_epochs = 50
+>>> num_train_steps = len(train_ds) * num_epochs
+>>> learning_rate = 6e-5
+>>> weight_decay_rate = 0.01
+
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=learning_rate,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=weight_decay_rate,
+... num_warmup_steps=0,
+... )
+```
+
+次に、ラベル マッピングとともに [`TFAutoModelForSemanticSegmentation`] を使用して SegFormer をロードし、それをコンパイルします。
+オプティマイザ。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
+
+```py
+>>> from transformers import TFAutoModelForSemanticSegmentation
+
+>>> model = TFAutoModelForSemanticSegmentation.from_pretrained(
+... checkpoint,
+... id2label=id2label,
+... label2id=label2id,
+... )
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+[`~datasets.Dataset.to_tf_dataset`] と [`DefaultDataCollator`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+
+>>> tf_train_dataset = train_ds.to_tf_dataset(
+... columns=["pixel_values", "label"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+
+>>> tf_eval_dataset = test_ds.to_tf_dataset(
+... columns=["pixel_values", "label"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+```
+
+予測から精度を計算し、モデルを 🤗 ハブにプッシュするには、[Keras callbacks](../main_classes/keras_callbacks) を使用します。
+`compute_metrics` 関数を [`KerasMetricCallback`] に渡します。
+そして [`PushToHubCallback`] を使用してモデルをアップロードします。
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback, PushToHubCallback
+
+>>> metric_callback = KerasMetricCallback(
+... metric_fn=compute_metrics, eval_dataset=tf_eval_dataset, batch_size=batch_size, label_cols=["labels"]
+... )
+
+>>> push_to_hub_callback = PushToHubCallback(output_dir="scene_segmentation", tokenizer=image_processor)
+
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+ついに、モデルをトレーニングする準備が整いました。トレーニングおよび検証データセット、エポック数、
+モデルを微調整するためのコールバック:
+
+
+```py
+>>> model.fit(
+... tf_train_dataset,
+... validation_data=tf_eval_dataset,
+... callbacks=callbacks,
+... epochs=num_epochs,
+... )
+```
+
+おめでとう!モデルを微調整し、🤗 Hub で共有しました。これで推論に使用できるようになりました。
+
+
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+推論のために画像をロードします。
+
+```py
+>>> image = ds[0]["image"]
+>>> image
+```
+
+
+
+
+
+
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して画像セグメンテーション用の `pipeline`をインスタンス化し、それに画像を渡します。
+
+```py
+>>> from transformers import pipeline
+
+>>> segmenter = pipeline("image-segmentation", model="my_awesome_seg_model")
+>>> segmenter(image)
+[{'score': None,
+ 'label': 'wall',
+ 'mask': },
+ {'score': None,
+ 'label': 'sky',
+ 'mask': },
+ {'score': None,
+ 'label': 'floor',
+ 'mask': },
+ {'score': None,
+ 'label': 'ceiling',
+ 'mask': },
+ {'score': None,
+ 'label': 'bed ',
+ 'mask': },
+ {'score': None,
+ 'label': 'windowpane',
+ 'mask': },
+ {'score': None,
+ 'label': 'cabinet',
+ 'mask': },
+ {'score': None,
+ 'label': 'chair',
+ 'mask': },
+ {'score': None,
+ 'label': 'armchair',
+ 'mask': }]
+```
+
+必要に応じて、`pipeline`の結果を手動で複製することもできます。画像を画像プロセッサで処理し、`pixel_values` を GPU に配置します。
+
+```py
+>>> device = torch.device("cuda" if torch.cuda.is_available() else "cpu") # use GPU if available, otherwise use a CPU
+>>> encoding = image_processor(image, return_tensors="pt")
+>>> pixel_values = encoding.pixel_values.to(device)
+```
+
+入力をモデルに渡し、`logits`を返します。
+
+
+```py
+>>> outputs = model(pixel_values=pixel_values)
+>>> logits = outputs.logits.cpu()
+```
+
+次に、ロジットを元の画像サイズに再スケールします。
+
+```py
+>>> upsampled_logits = nn.functional.interpolate(
+... logits,
+... size=image.size[::-1],
+... mode="bilinear",
+... align_corners=False,
+... )
+
+>>> pred_seg = upsampled_logits.argmax(dim=1)[0]
+```
+
+
+
+
+
+
+
+画像プロセッサをロードして画像を前処理し、入力を TensorFlow テンソルとして返します。
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("MariaK/scene_segmentation")
+>>> inputs = image_processor(image, return_tensors="tf")
+```
+
+入力をモデルに渡し、`logits`を返します。
+
+```py
+>>> from transformers import TFAutoModelForSemanticSegmentation
+
+>>> model = TFAutoModelForSemanticSegmentation.from_pretrained("MariaK/scene_segmentation")
+>>> logits = model(**inputs).logits
+```
+
+次に、ロジットを元の画像サイズに再スケールし、クラス次元に argmax を適用します。
+
+```py
+>>> logits = tf.transpose(logits, [0, 2, 3, 1])
+
+>>> upsampled_logits = tf.image.resize(
+... logits,
+... # We reverse the shape of `image` because `image.size` returns width and height.
+... image.size[::-1],
+... )
+
+>>> pred_seg = tf.math.argmax(upsampled_logits, axis=-1)[0]
+```
+
+
+
+
+結果を視覚化するには、[データセット カラー パレット](https://github.com/tensorflow/models/blob/3f1ca33afe3c1631b733ea7e40c294273b9e406d/research/deeplab/utils/get_dataset_colormap.py#L51) を、それぞれをマップする `ade_palette()` としてロードします。クラスを RGB 値に変換します。次に、画像と予測されたセグメンテーション マップを組み合わせてプロットできます。
+
+```py
+>>> import matplotlib.pyplot as plt
+>>> import numpy as np
+
+>>> color_seg = np.zeros((pred_seg.shape[0], pred_seg.shape[1], 3), dtype=np.uint8)
+>>> palette = np.array(ade_palette())
+>>> for label, color in enumerate(palette):
+... color_seg[pred_seg == label, :] = color
+>>> color_seg = color_seg[..., ::-1] # convert to BGR
+
+>>> img = np.array(image) * 0.5 + color_seg * 0.5 # plot the image with the segmentation map
+>>> img = img.astype(np.uint8)
+
+>>> plt.figure(figsize=(15, 10))
+>>> plt.imshow(img)
+>>> plt.show()
+```
+
+
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/text-classification) を確認することをお勧めします。
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install -q datasets transformers evaluate
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load SceneParse150 dataset
+
+
+まず、SceneParse150 データセットの小さいサブセットを 🤗 データセット ライブラリから読み込みます。これにより、完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
+
+```py
+>>> from datasets import load_dataset
+
+>>> ds = load_dataset("scene_parse_150", split="train[:50]")
+```
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train` 分割をトレイン セットとテスト セットに分割します。
+
+```py
+>>> ds = ds.train_test_split(test_size=0.2)
+>>> train_ds = ds["train"]
+>>> test_ds = ds["test"]
+```
+
+次に、例を見てみましょう。
+
+```py
+>>> train_ds[0]
+{'image': ,
+ 'annotation': ,
+ 'scene_category': 368}
+```
+
+- `image`: シーンの PIL イメージ。
+- `annotation`: セグメンテーション マップの PIL イメージ。モデルのターゲットでもあります。
+- `scene_category`: 「キッチン」や「オフィス」などの画像シーンを説明するカテゴリ ID。このガイドでは、「image」と「annotation」のみが必要になります。どちらも PIL イメージです。
+
+また、ラベル ID をラベル クラスにマップする辞書を作成することもできます。これは、後でモデルを設定するときに役立ちます。ハブからマッピングをダウンロードし、`id2label` および `label2id` ディクショナリを作成します。
+
+```py
+>>> import json
+>>> from pathlib import Path
+>>> from huggingface_hub import hf_hub_download
+
+>>> repo_id = "huggingface/label-files"
+>>> filename = "ade20k-id2label.json"
+>>> id2label = json.loads(Path(hf_hub_download(repo_id, filename, repo_type="dataset")).read_text())
+>>> id2label = {int(k): v for k, v in id2label.items()}
+>>> label2id = {v: k for k, v in id2label.items()}
+>>> num_labels = len(id2label)
+```
+
+## Preprocess
+
+次のステップでは、SegFormer 画像プロセッサをロードして、モデルの画像と注釈を準備します。このデータセットのような一部のデータセットは、バックグラウンド クラスとしてゼロインデックスを使用します。ただし、実際には背景クラスは 150 個のクラスに含まれていないため、`do_reduce_labels=True`を設定してすべてのラベルから 1 つを引く必要があります。ゼロインデックスは `255` に置き換えられるため、SegFormer の損失関数によって無視されます。
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> checkpoint = "nvidia/mit-b0"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint, do_reduce_labels=True)
+```
+
+
+
+
+モデルを過学習に対してより堅牢にするために、画像データセットにいくつかのデータ拡張を適用するのが一般的です。このガイドでは、[torchvision](https://pytorch.org) の [`ColorJitter`](https://pytorch.org/vision/stable/generated/torchvision.transforms.ColorJitter.html) 関数を使用します。 /vision/stable/index.html) を使用して画像の色のプロパティをランダムに変更しますが、任意の画像ライブラリを使用することもできます。
+
+```py
+>>> from torchvision.transforms import ColorJitter
+
+>>> jitter = ColorJitter(brightness=0.25, contrast=0.25, saturation=0.25, hue=0.1)
+```
+
+次に、モデルの画像と注釈を準備するための 2 つの前処理関数を作成します。これらの関数は、画像を`pixel_values`に変換し、注釈を`labels`に変換します。トレーニング セットの場合、画像を画像プロセッサに提供する前に`jitter`が適用されます。テスト セットの場合、テスト中にデータ拡張が適用されないため、画像プロセッサは`images`を切り取って正規化し、`labels` のみを切り取ります。
+
+```py
+>>> def train_transforms(example_batch):
+... images = [jitter(x) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+
+
+>>> def val_transforms(example_batch):
+... images = [x for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+```
+
+データセット全体に`jitter`を適用するには、🤗 Datasets [`~datasets.Dataset.set_transform`] 関数を使用します。変換はオンザフライで適用されるため、高速で消費するディスク容量が少なくなります。
+
+```py
+>>> train_ds.set_transform(train_transforms)
+>>> test_ds.set_transform(val_transforms)
+```
+
+
+
+
+
+
+
+モデルを過学習に対してより堅牢にするために、画像データセットにいくつかのデータ拡張を適用するのが一般的です。
+このガイドでは、[`tf.image`](https://www.tensorflow.org/api_docs/python/tf/image) を使用して画像の色のプロパティをランダムに変更しますが、任意のプロパティを使用することもできます。画像
+好きな図書館。
+2 つの別々の変換関数を定義します。
+- 画像拡張を含むトレーニング データ変換
+- 🤗 Transformers のコンピューター ビジョン モデルはチャネル優先のレイアウトを想定しているため、画像を転置するだけの検証データ変換
+
+```py
+>>> import tensorflow as tf
+
+
+>>> def aug_transforms(image):
+... image = tf.keras.utils.img_to_array(image)
+... image = tf.image.random_brightness(image, 0.25)
+... image = tf.image.random_contrast(image, 0.5, 2.0)
+... image = tf.image.random_saturation(image, 0.75, 1.25)
+... image = tf.image.random_hue(image, 0.1)
+... image = tf.transpose(image, (2, 0, 1))
+... return image
+
+
+>>> def transforms(image):
+... image = tf.keras.utils.img_to_array(image)
+... image = tf.transpose(image, (2, 0, 1))
+... return image
+```
+
+次に、モデルの画像と注釈のバッチを準備する 2 つの前処理関数を作成します。これらの機能が適用されます
+画像変換を行い、以前にロードされた `image_processor` を使用して画像を `pixel_values` に変換し、
+`labels`への注釈。 `ImageProcessor` は、画像のサイズ変更と正規化も処理します。
+
+```py
+>>> def train_transforms(example_batch):
+... images = [aug_transforms(x.convert("RGB")) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+
+
+>>> def val_transforms(example_batch):
+... images = [transforms(x.convert("RGB")) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+```
+
+データセット全体に前処理変換を適用するには、🤗 Datasets [`~datasets.Dataset.set_transform`] 関数を使用します。
+変換はオンザフライで適用されるため、高速で消費するディスク容量が少なくなります。
+
+```py
+>>> train_ds.set_transform(train_transforms)
+>>> test_ds.set_transform(val_transforms)
+```
+
+
+
+## Evaluate
+
+トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[Mean Intersection over Union](https://huggingface.co/spaces/evaluate-metric/accuracy) (IoU) メトリックをロードします (🤗 Evaluate [クイック ツアー](https://huggingface.co) を参照してください) /docs/evaluate/a_quick_tour) を参照して、メトリクスをロードして計算する方法の詳細を確認してください)。
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("mean_iou")
+```
+
+次に、メトリクスを [`~evaluate.EvaluationModule.compute`] する関数を作成します。予測を次のように変換する必要があります
+最初にロジットを作成し、次に [`~evaluate.EvaluationModule.compute`] を呼び出す前にラベルのサイズに一致するように再形成します。
+
+
+
+
+```py
+>>> import numpy as np
+>>> import torch
+>>> from torch import nn
+
+>>> def compute_metrics(eval_pred):
+... with torch.no_grad():
+... logits, labels = eval_pred
+... logits_tensor = torch.from_numpy(logits)
+... logits_tensor = nn.functional.interpolate(
+... logits_tensor,
+... size=labels.shape[-2:],
+... mode="bilinear",
+... align_corners=False,
+... ).argmax(dim=1)
+
+... pred_labels = logits_tensor.detach().cpu().numpy()
+... metrics = metric.compute(
+... predictions=pred_labels,
+... references=labels,
+... num_labels=num_labels,
+... ignore_index=255,
+... reduce_labels=False,
+... )
+... for key, value in metrics.items():
+... if type(value) is np.ndarray:
+... metrics[key] = value.tolist()
+... return metrics
+```
+
+
+
+
+
+
+
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... logits = tf.transpose(logits, perm=[0, 2, 3, 1])
+... logits_resized = tf.image.resize(
+... logits,
+... size=tf.shape(labels)[1:],
+... method="bilinear",
+... )
+
+... pred_labels = tf.argmax(logits_resized, axis=-1)
+... metrics = metric.compute(
+... predictions=pred_labels,
+... references=labels,
+... num_labels=num_labels,
+... ignore_index=-1,
+... reduce_labels=image_processor.do_reduce_labels,
+... )
+
+... per_category_accuracy = metrics.pop("per_category_accuracy").tolist()
+... per_category_iou = metrics.pop("per_category_iou").tolist()
+
+... metrics.update({f"accuracy_{id2label[i]}": v for i, v in enumerate(per_category_accuracy)})
+... metrics.update({f"iou_{id2label[i]}": v for i, v in enumerate(per_category_iou)})
+... return {"val_" + k: v for k, v in metrics.items()}
+```
+
+
+
+
+これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
+
+## Train
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[こちら](../training#finetune-with-trainer) の基本的なチュートリアルをご覧ください。
+
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForSemanticSegmentation`] を使用して SegFormer をロードし、ラベル ID とラベル クラス間のマッピングをモデルに渡します。
+
+```py
+>>> from transformers import AutoModelForSemanticSegmentation, TrainingArguments, Trainer
+
+>>> model = AutoModelForSemanticSegmentation.from_pretrained(checkpoint, id2label=id2label, label2id=label2id)
+```
+
+この時点で残っている手順は次の 3 つだけです。
+
+1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。 `image` 列が削除されるため、未使用の列を削除しないことが重要です。 `image` 列がないと、`pixel_values` を作成できません。この動作を防ぐには、`remove_unused_columns=False`を設定してください。他に必要なパラメータは、モデルの保存場所を指定する `output_dir` だけです。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`Trainer`] は IoU メトリックを評価し、トレーニング チェックポイントを保存します。
+2. トレーニング引数を、モデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Trainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="segformer-b0-scene-parse-150",
+... learning_rate=6e-5,
+... num_train_epochs=50,
+... per_device_train_batch_size=2,
+... per_device_eval_batch_size=2,
+... save_total_limit=3,
+... eval_strategy="steps",
+... save_strategy="steps",
+... save_steps=20,
+... eval_steps=20,
+... logging_steps=1,
+... eval_accumulation_steps=5,
+... remove_unused_columns=False,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=train_ds,
+... eval_dataset=test_ds,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+
+
+Keras を使用したモデルの微調整に慣れていない場合は、まず [基本チュートリアル](./training#train-a-tensorflow-model-with-keras) を確認してください。
+
+
+
+TensorFlow でモデルを微調整するには、次の手順に従います。
+1. トレーニングのハイパーパラメータを定義し、オプティマイザーと学習率スケジュールを設定します。
+2. 事前トレーニングされたモデルをインスタンス化します。
+3. 🤗 データセットを `tf.data.Dataset` に変換します。
+4. モデルをコンパイルします。
+5. コールバックを追加してメトリクスを計算し、モデルを 🤗 Hub にアップロードします
+6. `fit()` メソッドを使用してトレーニングを実行します。
+
+まず、ハイパーパラメーター、オプティマイザー、学習率スケジュールを定義します。
+
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 2
+>>> num_epochs = 50
+>>> num_train_steps = len(train_ds) * num_epochs
+>>> learning_rate = 6e-5
+>>> weight_decay_rate = 0.01
+
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=learning_rate,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=weight_decay_rate,
+... num_warmup_steps=0,
+... )
+```
+
+次に、ラベル マッピングとともに [`TFAutoModelForSemanticSegmentation`] を使用して SegFormer をロードし、それをコンパイルします。
+オプティマイザ。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
+
+```py
+>>> from transformers import TFAutoModelForSemanticSegmentation
+
+>>> model = TFAutoModelForSemanticSegmentation.from_pretrained(
+... checkpoint,
+... id2label=id2label,
+... label2id=label2id,
+... )
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+[`~datasets.Dataset.to_tf_dataset`] と [`DefaultDataCollator`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+
+>>> tf_train_dataset = train_ds.to_tf_dataset(
+... columns=["pixel_values", "label"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+
+>>> tf_eval_dataset = test_ds.to_tf_dataset(
+... columns=["pixel_values", "label"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+```
+
+予測から精度を計算し、モデルを 🤗 ハブにプッシュするには、[Keras callbacks](../main_classes/keras_callbacks) を使用します。
+`compute_metrics` 関数を [`KerasMetricCallback`] に渡します。
+そして [`PushToHubCallback`] を使用してモデルをアップロードします。
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback, PushToHubCallback
+
+>>> metric_callback = KerasMetricCallback(
+... metric_fn=compute_metrics, eval_dataset=tf_eval_dataset, batch_size=batch_size, label_cols=["labels"]
+... )
+
+>>> push_to_hub_callback = PushToHubCallback(output_dir="scene_segmentation", image_processor=image_processor)
+
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+ついに、モデルをトレーニングする準備が整いました。`fit()`トレーニングおよび検証データセット、エポック数、
+モデルを微調整するためのコールバック:
+
+```py
+>>> model.fit(
+... tf_train_dataset,
+... validation_data=tf_eval_dataset,
+... callbacks=callbacks,
+... epochs=num_epochs,
+... )
+```
+
+おめでとう!モデルを微調整し、🤗 Hub で共有しました。これで推論に使用できるようになりました。
+
+
+
+
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+推論のために画像をロードします。
+
+```py
+>>> image = ds[0]["image"]
+>>> image
+```
+
+
+
+
+
+
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して画像セグメンテーション用の `pipeline` をインスタンス化し、それに画像を渡します。
+
+```py
+>>> from transformers import pipeline
+
+>>> segmenter = pipeline("image-segmentation", model="my_awesome_seg_model")
+>>> segmenter(image)
+[{'score': None,
+ 'label': 'wall',
+ 'mask': },
+ {'score': None,
+ 'label': 'sky',
+ 'mask': },
+ {'score': None,
+ 'label': 'floor',
+ 'mask': },
+ {'score': None,
+ 'label': 'ceiling',
+ 'mask': },
+ {'score': None,
+ 'label': 'bed ',
+ 'mask': },
+ {'score': None,
+ 'label': 'windowpane',
+ 'mask': },
+ {'score': None,
+ 'label': 'cabinet',
+ 'mask': },
+ {'score': None,
+ 'label': 'chair',
+ 'mask': },
+ {'score': None,
+ 'label': 'armchair',
+ 'mask': }]
+```
+
+必要に応じて、`pipeline` の結果を手動で複製することもできます。画像プロセッサで画像を処理し、`pixel_values`を GPU に配置します。
+
+```py
+>>> device = torch.device("cuda" if torch.cuda.is_available() else "cpu") # use GPU if available, otherwise use a CPU
+>>> encoding = image_processor(image, return_tensors="pt")
+>>> pixel_values = encoding.pixel_values.to(device)
+```
+
+入力をモデルに渡し、「logits」を返します。
+
+```py
+>>> outputs = model(pixel_values=pixel_values)
+>>> logits = outputs.logits.cpu()
+```
+
+次に、ロジットを元の画像サイズに再スケールします。
+
+
+```py
+>>> upsampled_logits = nn.functional.interpolate(
+... logits,
+... size=image.size[::-1],
+... mode="bilinear",
+... align_corners=False,
+... )
+
+>>> pred_seg = upsampled_logits.argmax(dim=1)[0]
+```
+
+
+
+
+
+
+
+画像プロセッサをロードして画像を前処理し、入力を TensorFlow テンソルとして返します。
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("MariaK/scene_segmentation")
+>>> inputs = image_processor(image, return_tensors="tf")
+```
+
+入力をモデルに渡し、`logits`を返します。
+
+```py
+>>> from transformers import TFAutoModelForSemanticSegmentation
+
+>>> model = TFAutoModelForSemanticSegmentation.from_pretrained("MariaK/scene_segmentation")
+>>> logits = model(**inputs).logits
+```
+
+次に、ロジットを元の画像サイズに再スケールし、クラス次元に argmax を適用します。
+
+```py
+>>> logits = tf.transpose(logits, [0, 2, 3, 1])
+
+>>> upsampled_logits = tf.image.resize(
+... logits,
+... # We reverse the shape of `image` because `image.size` returns width and height.
+... image.size[::-1],
+... )
+
+>>> pred_seg = tf.math.argmax(upsampled_logits, axis=-1)[0]
+```
+
+
+
+
+結果を視覚化するには、[データセット カラー パレット](https://github.com/tensorflow/models/blob/3f1ca33afe3c1631b733ea7e40c294273b9e406d/research/deeplab/utils/get_dataset_colormap.py#L51) を、それぞれをマップする `ade_palette()` としてロードします。クラスを RGB 値に変換します。次に、画像と予測されたセグメンテーション マップを組み合わせてプロットできます。
+
+```py
+>>> import matplotlib.pyplot as plt
+>>> import numpy as np
+
+>>> color_seg = np.zeros((pred_seg.shape[0], pred_seg.shape[1], 3), dtype=np.uint8)
+>>> palette = np.array(ade_palette())
+>>> for label, color in enumerate(palette):
+... color_seg[pred_seg == label, :] = color
+>>> color_seg = color_seg[..., ::-1] # convert to BGR
+
+>>> img = np.array(image) * 0.5 + color_seg * 0.5 # plot the image with the segmentation map
+>>> img = img.astype(np.uint8)
+
+>>> plt.figure(figsize=(15, 10))
+>>> plt.imshow(img)
+>>> plt.show()
+```
+
+
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/summarization) を確認することをお勧めします。
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install transformers datasets evaluate rouge_score
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load BillSum dataset
+
+まず、🤗 データセット ライブラリから BillSum データセットの小さいカリフォルニア州請求書サブセットを読み込みます。
+
+```py
+>>> from datasets import load_dataset
+
+>>> billsum = load_dataset("billsum", split="ca_test")
+```
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットをトレイン セットとテスト セットに分割します。
+
+```py
+>>> billsum = billsum.train_test_split(test_size=0.2)
+```
+
+次に、例を見てみましょう。
+
+```py
+>>> billsum["train"][0]
+{'summary': 'Existing law authorizes state agencies to enter into contracts for the acquisition of goods or services upon approval by the Department of General Services. Existing law sets forth various requirements and prohibitions for those contracts, including, but not limited to, a prohibition on entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between spouses and domestic partners or same-sex and different-sex couples in the provision of benefits. Existing law provides that a contract entered into in violation of those requirements and prohibitions is void and authorizes the state or any person acting on behalf of the state to bring a civil action seeking a determination that a contract is in violation and therefore void. Under existing law, a willful violation of those requirements and prohibitions is a misdemeanor.\nThis bill would also prohibit a state agency from entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between employees on the basis of gender identity in the provision of benefits, as specified. By expanding the scope of a crime, this bill would impose a state-mandated local program.\nThe California Constitution requires the state to reimburse local agencies and school districts for certain costs mandated by the state. Statutory provisions establish procedures for making that reimbursement.\nThis bill would provide that no reimbursement is required by this act for a specified reason.',
+ 'text': 'The people of the State of California do enact as follows:\n\n\nSECTION 1.\nSection 10295.35 is added to the Public Contract Code, to read:\n10295.35.\n(a) (1) Notwithstanding any other law, a state agency shall not enter into any contract for the acquisition of goods or services in the amount of one hundred thousand dollars ($100,000) or more with a contractor that, in the provision of benefits, discriminates between employees on the basis of an employee’s or dependent’s actual or perceived gender identity, including, but not limited to, the employee’s or dependent’s identification as transgender.\n(2) For purposes of this section, “contract” includes contracts with a cumulative amount of one hundred thousand dollars ($100,000) or more per contractor in each fiscal year.\n(3) For purposes of this section, an employee health plan is discriminatory if the plan is not consistent with Section 1365.5 of the Health and Safety Code and Section 10140 of the Insurance Code.\n(4) The requirements of this section shall apply only to those portions of a contractor’s operations that occur under any of the following conditions:\n(A) Within the state.\n(B) On real property outside the state if the property is owned by the state or if the state has a right to occupy the property, and if the contractor’s presence at that location is connected to a contract with the state.\n(C) Elsewhere in the United States where work related to a state contract is being performed.\n(b) Contractors shall treat as confidential, to the maximum extent allowed by law or by the requirement of the contractor’s insurance provider, any request by an employee or applicant for employment benefits or any documentation of eligibility for benefits submitted by an employee or applicant for employment.\n(c) After taking all reasonable measures to find a contractor that complies with this section, as determined by the state agency, the requirements of this section may be waived under any of the following circumstances:\n(1) There is only one prospective contractor willing to enter into a specific contract with the state agency.\n(2) The contract is necessary to respond to an emergency, as determined by the state agency, that endangers the public health, welfare, or safety, or the contract is necessary for the provision of essential services, and no entity that complies with the requirements of this section capable of responding to the emergency is immediately available.\n(3) The requirements of this section violate, or are inconsistent with, the terms or conditions of a grant, subvention, or agreement, if the agency has made a good faith attempt to change the terms or conditions of any grant, subvention, or agreement to authorize application of this section.\n(4) The contractor is providing wholesale or bulk water, power, or natural gas, the conveyance or transmission of the same, or ancillary services, as required for ensuring reliable services in accordance with good utility practice, if the purchase of the same cannot practically be accomplished through the standard competitive bidding procedures and the contractor is not providing direct retail services to end users.\n(d) (1) A contractor shall not be deemed to discriminate in the provision of benefits if the contractor, in providing the benefits, pays the actual costs incurred in obtaining the benefit.\n(2) If a contractor is unable to provide a certain benefit, despite taking reasonable measures to do so, the contractor shall not be deemed to discriminate in the provision of benefits.\n(e) (1) Every contract subject to this chapter shall contain a statement by which the contractor certifies that the contractor is in compliance with this section.\n(2) The department or other contracting agency shall enforce this section pursuant to its existing enforcement powers.\n(3) (A) If a contractor falsely certifies that it is in compliance with this section, the contract with that contractor shall be subject to Article 9 (commencing with Section 10420), unless, within a time period specified by the department or other contracting agency, the contractor provides to the department or agency proof that it has complied, or is in the process of complying, with this section.\n(B) The application of the remedies or penalties contained in Article 9 (commencing with Section 10420) to a contract subject to this chapter shall not preclude the application of any existing remedies otherwise available to the department or other contracting agency under its existing enforcement powers.\n(f) Nothing in this section is intended to regulate the contracting practices of any local jurisdiction.\n(g) This section shall be construed so as not to conflict with applicable federal laws, rules, or regulations. In the event that a court or agency of competent jurisdiction holds that federal law, rule, or regulation invalidates any clause, sentence, paragraph, or section of this code or the application thereof to any person or circumstances, it is the intent of the state that the court or agency sever that clause, sentence, paragraph, or section so that the remainder of this section shall remain in effect.\nSEC. 2.\nSection 10295.35 of the Public Contract Code shall not be construed to create any new enforcement authority or responsibility in the Department of General Services or any other contracting agency.\nSEC. 3.\nNo reimbursement is required by this act pursuant to Section 6 of Article XIII\u2009B of the California Constitution because the only costs that may be incurred by a local agency or school district will be incurred because this act creates a new crime or infraction, eliminates a crime or infraction, or changes the penalty for a crime or infraction, within the meaning of Section 17556 of the Government Code, or changes the definition of a crime within the meaning of Section 6 of Article XIII\u2009B of the California Constitution.',
+ 'title': 'An act to add Section 10295.35 to the Public Contract Code, relating to public contracts.'}
+```
+
+使用するフィールドが 2 つあります。
+
+- `text`: モデルへの入力となる請求書のテキスト。
+- `summary`: モデルのターゲットとなる `text` の要約版。
+
+## Preprocess
+
+次のステップでは、T5 トークナイザーをロードして「text」と`summary`を処理します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> checkpoint = "google-t5/t5-small"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+```
+
+作成する前処理関数は次のことを行う必要があります。
+
+1. T5 がこれが要約タスクであることを認識できるように、入力の前にプロンプトを付けます。複数の NLP タスクが可能な一部のモデルでは、特定のタスクのプロンプトが必要です。
+2. ラベルをトークン化するときにキーワード `text_target` 引数を使用します。
+3. `max_length`パラメータで設定された最大長を超えないようにシーケンスを切り詰めます。
+
+```py
+>>> prefix = "summarize: "
+
+
+>>> def preprocess_function(examples):
+... inputs = [prefix + doc for doc in examples["text"]]
+... model_inputs = tokenizer(inputs, max_length=1024, truncation=True)
+
+... labels = tokenizer(text_target=examples["summary"], max_length=128, truncation=True)
+
+... model_inputs["labels"] = labels["input_ids"]
+... return model_inputs
+```
+
+データセット全体に前処理関数を適用するには、🤗 Datasets [`~datasets.Dataset.map`] メソッドを使用します。 `batched=True` を設定してデータセットの複数の要素を一度に処理することで、`map` 関数を高速化できます。
+
+```py
+>>> tokenized_billsum = billsum.map(preprocess_function, batched=True)
+```
+
+次に、[`DataCollatorForSeq2Seq`] を使用してサンプルのバッチを作成します。データセット全体を最大長までパディングするのではなく、照合中にバッチ内の最長の長さまで文を *動的にパディング* する方が効率的です。
+
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint)
+```
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint, return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[ROUGE](https://huggingface.co/spaces/evaluate-metric/rouge) メトリックを読み込みます (🤗 Evaluate [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照してください) ) メトリクスをロードして計算する方法の詳細については、次を参照してください)。
+
+```py
+>>> import evaluate
+
+>>> rouge = evaluate.load("rouge")
+```
+
+次に、予測とラベルを [`~evaluate.EvaluationModule.compute`] に渡して ROUGE メトリクスを計算する関数を作成します。
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... decoded_preds = tokenizer.batch_decode(predictions, skip_special_tokens=True)
+... labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+... decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+... result = rouge.compute(predictions=decoded_preds, references=decoded_labels, use_stemmer=True)
+
+... prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in predictions]
+... result["gen_len"] = np.mean(prediction_lens)
+
+... return {k: round(v, 4) for k, v in result.items()}
+```
+
+これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
+
+## Train
+
+
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForSeq2SeqLM`] を使用して T5 をロードします。
+
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM, Seq2SeqTrainingArguments, Seq2SeqTrainer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+この時点で残っている手順は次の 3 つだけです。
+
+1. [`Seq2SeqTrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`Trainer`] は ROUGE メトリクスを評価し、トレーニング チェックポイントを保存します。
+2. トレーニング引数をモデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Seq2SeqTrainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+```py
+>>> training_args = Seq2SeqTrainingArguments(
+... output_dir="my_awesome_billsum_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... weight_decay=0.01,
+... save_total_limit=3,
+... num_train_epochs=4,
+... predict_with_generate=True,
+... fp16=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Seq2SeqTrainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_billsum["train"],
+... eval_dataset=tokenized_billsum["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-a-tensorflow-model-with-keras) の基本的なチュートリアルをご覧ください。
+
+
+TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+次に、[`TFAutoModelForSeq2SeqLM`] を使用して T5 をロードできます。
+
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_billsum["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... tokenized_billsum["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+トレーニングを開始する前にセットアップする最後の 2 つのことは、予測から ROUGE スコアを計算し、モデルをハブにプッシュする方法を提供することです。どちらも [Keras コールバック](../main_classes/keras_callbacks) を使用して行われます。
+
+`compute_metrics` 関数を [`~transformers.KerasMetricCallback`] に渡します。
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+Specify where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_billsum_model",
+... tokenizer=tokenizer,
+... )
+```
+
+次に、コールバックをまとめてバンドルします。
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=callbacks)
+```
+
+トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
+
+
+
+
+
+
+要約用にモデルを微調整する方法のより詳細な例については、対応するセクションを参照してください。
+[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization.ipynb)
+または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization-tf.ipynb)。
+
+
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+要約したいテキストを考え出します。 T5 の場合、作業中のタスクに応じて入力に接頭辞を付ける必要があります。要約するには、以下に示すように入力にプレフィックスを付ける必要があります。
+
+```py
+>>> text = "summarize: The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country. It'll lower the deficit and ask the ultra-wealthy and corporations to pay their fair share. And no one making under $400,000 per year will pay a penny more in taxes."
+```
+
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して要約用の `pipeline` をインスタンス化し、テキストをそれに渡します。
+
+```py
+>>> from transformers import pipeline
+
+>>> summarizer = pipeline("summarization", model="stevhliu/my_awesome_billsum_model")
+>>> summarizer(text)
+[{"summary_text": "The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country."}]
+```
+
+必要に応じて、`pipeline`」の結果を手動で複製することもできます。
+
+
+
+Tokenize the text and return the `input_ids` as PyTorch tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> inputs = tokenizer(text, return_tensors="pt").input_ids
+```
+
+[`~generation.GenerationMixin.generate`] メソッドを使用して要約を作成します。さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[Text Generation](../main_classes/text_generation) API を確認してください。
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
+```
+
+生成されたトークン ID をデコードしてテキストに戻します。
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
+```
+
+
+
+テキストをトークン化し、`input_ids`を TensorFlow テンソルとして返します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> inputs = tokenizer(text, return_tensors="tf").input_ids
+```
+
+[`~transformers.generation_tf_utils.TFGenerationMixin.generate`] メソッドを使用して要約を作成します。さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[Text Generation](../main_classes/text_generation) API を確認してください。
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
+```
+
+生成されたトークン ID をデコードしてテキストに戻します。
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/text-to-speech.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/text-to-speech.md
new file mode 100644
index 0000000000000000000000000000000000000000..669d15730e24f892e27103a9ad48733b5e7fb34d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/text-to-speech.md
@@ -0,0 +1,638 @@
+
+
+# Text to speech
+
+[[open-in-colab]]
+
+テキスト読み上げ (TTS) は、テキストから自然な音声を作成するタスクです。音声は複数の形式で生成できます。
+言語と複数の話者向け。現在、いくつかのテキスト読み上げモデルが 🤗 Transformers で利用可能です。
+[Bark](../model_doc/bark)、[MMS](../model_doc/mms)、[VITS](../model_doc/vits)、および [SpeechT5](../model_doc/speecht5)。
+
+`text-to-audio`パイプライン (またはその別名 - `text-to-speech`) を使用して、音声を簡単に生成できます。 Bark などの一部のモデルは、
+笑い、ため息、泣きなどの非言語コミュニケーションを生成したり、音楽を追加したりするように条件付けすることもできます。
+Bark で`text-to-speech`パイプラインを使用する方法の例を次に示します。
+
+```py
+>>> from transformers import pipeline
+
+>>> pipe = pipeline("text-to-speech", model="suno/bark-small")
+>>> text = "[clears throat] This is a test ... and I just took a long pause."
+>>> output = pipe(text)
+```
+
+ノートブックで結果の音声を聞くために使用できるコード スニペットを次に示します。
+
+```python
+>>> from IPython.display import Audio
+>>> Audio(output["audio"], rate=output["sampling_rate"])
+```
+Bark およびその他の事前トレーニングされた TTS モデルができることの詳細な例については、次のドキュメントを参照してください。
+[音声コース](https://huggingface.co/learn/audio-course/chapter6/pre-trained_models)。
+
+TTS モデルを微調整する場合、現在微調整できるのは SpeechT5 のみです。 SpeechT5 は、次の組み合わせで事前トレーニングされています。
+音声からテキストへのデータとテキストから音声へのデータ。両方のテキストに共有される隠された表現の統一された空間を学習できるようにします。
+そしてスピーチ。これは、同じ事前トレーニング済みモデルをさまざまなタスクに合わせて微調整できることを意味します。さらに、SpeechT5
+X ベクトル スピーカーの埋め込みを通じて複数のスピーカーをサポートします。
+
+このガイドの残りの部分では、次の方法を説明します。
+
+1. [VoxPopuli](https://huggingface.co/datasets/facebook/voxpopuli) のオランダ語 (`nl`) 言語サブセット上の英語音声で元々トレーニングされた [SpeechT5](../model_doc/speecht5) を微調整します。 データセット。
+2. パイプラインを使用するか直接使用するかの 2 つの方法のいずれかで、洗練されたモデルを推論に使用します。
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+
+```bash
+pip install datasets soundfile speechbrain accelerate
+```
+
+SpeechT5 のすべての機能がまだ正式リリースにマージされていないため、ソースから 🤗Transformers をインストールします。
+
+```bash
+pip install git+https://github.com/huggingface/transformers.git
+```
+
+
+
+このガイドに従うには、GPU が必要です。ノートブックで作業している場合は、次の行を実行して GPU が利用可能かどうかを確認します。
+
+```bash
+!nvidia-smi
+```
+
+
+
+Hugging Face アカウントにログインして、モデルをアップロードしてコミュニティと共有することをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load the dataset
+
+[VoxPopuli](https://huggingface.co/datasets/facebook/voxpopuli) は、以下で構成される大規模な多言語音声コーパスです。
+データは 2009 年から 2020 年の欧州議会のイベント記録をソースとしています。 15 件分のラベル付き音声文字起こしデータが含まれています。
+ヨーロッパの言語。このガイドではオランダ語のサブセットを使用していますが、自由に別のサブセットを選択してください。
+
+VoxPopuli またはその他の自動音声認識 (ASR) データセットは最適ではない可能性があることに注意してください。
+TTS モデルをトレーニングするためのオプション。過剰なバックグラウンドノイズなど、ASR にとって有益となる機能は次のとおりです。
+通常、TTS では望ましくありません。ただし、最高品質、多言語、マルチスピーカーの TTS データセットを見つけるのは非常に困難な場合があります。
+挑戦的。
+
+データをロードしましょう:
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("facebook/voxpopuli", "nl", split="train")
+>>> len(dataset)
+20968
+```
+
+微調整には 20968 個の例で十分です。 SpeechT5 はオーディオ データのサンプリング レートが 16 kHz であることを想定しているため、
+データセット内の例がこの要件を満たしていることを確認してください。
+
+
+```py
+dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+```
+
+## Preprocess the data
+
+使用するモデル チェックポイントを定義し、適切なプロセッサをロードすることから始めましょう。
+
+
+```py
+>>> from transformers import SpeechT5Processor
+
+>>> checkpoint = "microsoft/speecht5_tts"
+>>> processor = SpeechT5Processor.from_pretrained(checkpoint)
+```
+
+### Text cleanup for SpeechT5 tokenization
+
+
+まずはテキストデータをクリーンアップすることから始めます。テキストを処理するには、プロセッサのトークナイザー部分が必要です。
+
+```py
+>>> tokenizer = processor.tokenizer
+```
+
+データセットの例には、`raw_text`機能と `normalized_text`機能が含まれています。テキスト入力としてどの機能を使用するかを決めるときは、
+SpeechT5 トークナイザーには数値のトークンがないことを考慮してください。 `normalized_text`には数字が書かれています
+テキストとして出力します。したがって、これはより適切であり、入力テキストとして `normalized_text` を使用することをお勧めします。
+
+SpeechT5 は英語でトレーニングされているため、オランダ語のデータセット内の特定の文字を認識しない可能性があります。もし
+残っているように、これらの文字は ``トークンに変換されます。ただし、オランダ語では、`à`などの特定の文字は
+音節を強調することに慣れています。テキストの意味を保持するために、この文字を通常の`a`に置き換えることができます。
+
+サポートされていないトークンを識別するには、`SpeechT5Tokenizer`を使用してデータセット内のすべての一意の文字を抽出します。
+文字をトークンとして扱います。これを行うには、以下を連結する `extract_all_chars` マッピング関数を作成します。
+すべての例からの転写を 1 つの文字列にまとめ、それを文字セットに変換します。
+すべての文字起こしが一度に利用できるように、`dataset.map()`で`batched=True`と`batch_size=-1`を必ず設定してください。
+マッピング機能。
+
+```py
+>>> def extract_all_chars(batch):
+... all_text = " ".join(batch["normalized_text"])
+... vocab = list(set(all_text))
+... return {"vocab": [vocab], "all_text": [all_text]}
+
+
+>>> vocabs = dataset.map(
+... extract_all_chars,
+... batched=True,
+... batch_size=-1,
+... keep_in_memory=True,
+... remove_columns=dataset.column_names,
+... )
+
+>>> dataset_vocab = set(vocabs["vocab"][0])
+>>> tokenizer_vocab = {k for k, _ in tokenizer.get_vocab().items()}
+```
+
+これで、2 つの文字セットができました。1 つはデータセットの語彙を持ち、もう 1 つはトークナイザーの語彙を持ちます。
+データセット内でサポートされていない文字を特定するには、これら 2 つのセットの差分を取ることができます。結果として
+set には、データセットにはあるがトークナイザーには含まれていない文字が含まれます。
+
+```py
+>>> dataset_vocab - tokenizer_vocab
+{' ', 'à', 'ç', 'è', 'ë', 'í', 'ï', 'ö', 'ü'}
+```
+
+前の手順で特定されたサポートされていない文字を処理するには、これらの文字を
+有効なトークン。スペースはトークナイザーですでに `▁` に置き換えられているため、個別に処理する必要がないことに注意してください。
+
+```py
+>>> replacements = [
+... ("à", "a"),
+... ("ç", "c"),
+... ("è", "e"),
+... ("ë", "e"),
+... ("í", "i"),
+... ("ï", "i"),
+... ("ö", "o"),
+... ("ü", "u"),
+... ]
+
+
+>>> def cleanup_text(inputs):
+... for src, dst in replacements:
+... inputs["normalized_text"] = inputs["normalized_text"].replace(src, dst)
+... return inputs
+
+
+>>> dataset = dataset.map(cleanup_text)
+```
+
+テキスト内の特殊文字を扱ったので、今度は音声データに焦点を移します。
+
+### Speakers
+
+VoxPopuli データセットには複数の話者の音声が含まれていますが、データセットには何人の話者が含まれているのでしょうか?に
+これを決定すると、一意の話者の数と、各話者がデータセットに寄与する例の数を数えることができます。
+データセットには合計 20,968 個の例が含まれており、この情報により、分布をより深く理解できるようになります。
+講演者とデータ内の例。
+
+```py
+>>> from collections import defaultdict
+
+>>> speaker_counts = defaultdict(int)
+
+>>> for speaker_id in dataset["speaker_id"]:
+... speaker_counts[speaker_id] += 1
+```
+
+ヒストグラムをプロットすると、各話者にどれだけのデータがあるかを把握できます。
+
+```py
+>>> import matplotlib.pyplot as plt
+
+>>> plt.figure()
+>>> plt.hist(speaker_counts.values(), bins=20)
+>>> plt.ylabel("Speakers")
+>>> plt.xlabel("Examples")
+>>> plt.show()
+```
+
+
+
+
+
+
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/token-classification) を確認することをお勧めします。
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install transformers datasets evaluate seqeval
+```
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load WNUT 17 dataset
+
+まず、🤗 データセット ライブラリから WNUT 17 データセットをロードします。
+
+```py
+>>> from datasets import load_dataset
+
+>>> wnut = load_dataset("wnut_17")
+```
+
+次に、例を見てみましょう。
+
+```py
+>>> wnut["train"][0]
+{'id': '0',
+ 'ner_tags': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 7, 8, 8, 0, 7, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'tokens': ['@paulwalk', 'It', "'s", 'the', 'view', 'from', 'where', 'I', "'m", 'living', 'for', 'two', 'weeks', '.', 'Empire', 'State', 'Building', '=', 'ESB', '.', 'Pretty', 'bad', 'storm', 'here', 'last', 'evening', '.']
+}
+```
+
+`ner_tags`内の各数字はエンティティを表します。数値をラベル名に変換して、エンティティが何であるかを調べます。
+
+```py
+>>> label_list = wnut["train"].features[f"ner_tags"].feature.names
+>>> label_list
+[
+ "O",
+ "B-corporation",
+ "I-corporation",
+ "B-creative-work",
+ "I-creative-work",
+ "B-group",
+ "I-group",
+ "B-location",
+ "I-location",
+ "B-person",
+ "I-person",
+ "B-product",
+ "I-product",
+]
+```
+各 `ner_tag` の前に付く文字は、エンティティのトークンの位置を示します。
+
+- `B-` はエンティティの始まりを示します。
+- `I-` は、トークンが同じエンティティ内に含まれていることを示します (たとえば、`State` トークンは次のようなエンティティの一部です)
+ `Empire State Building`)。
+- `0` は、トークンがどのエンティティにも対応しないことを示します。
+
+## Preprocess
+
+
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer)
+```
+
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer, return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[seqeval](https://huggingface.co/spaces/evaluate-metric/seqeval) フレームワークを読み込みます (🤗 Evaluate [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照してください) ) メトリクスの読み込みと計算の方法について詳しくは、こちらをご覧ください)。 Seqeval は実際に、精度、再現率、F1、精度などのいくつかのスコアを生成します。
+
+```py
+>>> import evaluate
+
+>>> seqeval = evaluate.load("seqeval")
+```
+
+まず NER ラベルを取得してから、真の予測と真のラベルを [`~evaluate.EvaluationModule.compute`] に渡してスコアを計算する関数を作成します。
+
+```py
+>>> import numpy as np
+
+>>> labels = [label_list[i] for i in example[f"ner_tags"]]
+
+
+>>> def compute_metrics(p):
+... predictions, labels = p
+... predictions = np.argmax(predictions, axis=2)
+
+... true_predictions = [
+... [label_list[p] for (p, l) in zip(prediction, label) if l != -100]
+... for prediction, label in zip(predictions, labels)
+... ]
+... true_labels = [
+... [label_list[l] for (p, l) in zip(prediction, label) if l != -100]
+... for prediction, label in zip(predictions, labels)
+... ]
+
+... results = seqeval.compute(predictions=true_predictions, references=true_labels)
+... return {
+... "precision": results["overall_precision"],
+... "recall": results["overall_recall"],
+... "f1": results["overall_f1"],
+... "accuracy": results["overall_accuracy"],
+... }
+```
+
+これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
+
+## Train
+
+モデルのトレーニングを開始する前に、`id2label`と`label2id`を使用して、予想される ID とそのラベルのマップを作成します。
+```py
+>>> id2label = {
+... 0: "O",
+... 1: "B-corporation",
+... 2: "I-corporation",
+... 3: "B-creative-work",
+... 4: "I-creative-work",
+... 5: "B-group",
+... 6: "I-group",
+... 7: "B-location",
+... 8: "I-location",
+... 9: "B-person",
+... 10: "I-person",
+... 11: "B-product",
+... 12: "I-product",
+... }
+>>> label2id = {
+... "O": 0,
+... "B-corporation": 1,
+... "I-corporation": 2,
+... "B-creative-work": 3,
+... "I-creative-work": 4,
+... "B-group": 5,
+... "I-group": 6,
+... "B-location": 7,
+... "I-location": 8,
+... "B-person": 9,
+... "I-person": 10,
+... "B-product": 11,
+... "I-product": 12,
+... }
+```
+
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[ここ](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForTokenClassification`] を使用して、予期されるラベルの数とラベル マッピングを指定して DistilBERT を読み込みます。
+
+```py
+>>> from transformers import AutoModelForTokenClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForTokenClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=13, id2label=id2label, label2id=label2id
+... )
+```
+
+この時点で残っているステップは 3 つだけです。
+
+1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`Trainer`] は連続スコアを評価し、トレーニング チェックポイントを保存します。
+2. トレーニング引数を、モデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Trainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_wnut_model",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=2,
+... weight_decay=0.01,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... load_best_model_at_end=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_wnut["train"],
+... eval_dataset=tokenized_wnut["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-a-tensorflow-model-with-keras) の基本的なチュートリアルをご覧ください。
+
+
+TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_train_epochs = 3
+>>> num_train_steps = (len(tokenized_wnut["train"]) // batch_size) * num_train_epochs
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=2e-5,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=0.01,
+... num_warmup_steps=0,
+... )
+```
+次に、[`TFAutoModelForTokenClassification`] を使用して、予期されるラベルの数とラベル マッピングを指定して DistilBERT をロードできます。
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=13, id2label=id2label, label2id=label2id
+... )
+```
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_wnut["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_wnut["validation"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+トレーニングを開始する前にセットアップする最後の 2 つのことは、予測から連続スコアを計算することと、モデルをハブにプッシュする方法を提供することです。どちらも [Keras コールバック](../main_classes/keras_callbacks) を使用して行われます。
+
+`compute_metrics` 関数を [`~transformers.KerasMetricCallback`] に渡します。
+
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+[`~transformers.PushToHubCallback`] でモデルとトークナイザーをプッシュする場所を指定します。
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_wnut_model",
+... tokenizer=tokenizer,
+... )
+```
+
+次に、コールバックをまとめてバンドルします。
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
+
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=callbacks)
+```
+
+トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
+
+
+
+
+
+
+トークン分類のモデルを微調整する方法のより詳細な例については、対応するセクションを参照してください。
+[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb)
+または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification-tf.ipynb)。
+
+
+
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+推論を実行したいテキストをいくつか取得します。
+
+```py
+>>> text = "The Golden State Warriors are an American professional basketball team based in San Francisco."
+```
+
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して NER の`pipeline`をインスタンス化し、テキストをそれに渡します。
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("ner", model="stevhliu/my_awesome_wnut_model")
+>>> classifier(text)
+[{'entity': 'B-location',
+ 'score': 0.42658573,
+ 'index': 2,
+ 'word': 'golden',
+ 'start': 4,
+ 'end': 10},
+ {'entity': 'I-location',
+ 'score': 0.35856336,
+ 'index': 3,
+ 'word': 'state',
+ 'start': 11,
+ 'end': 16},
+ {'entity': 'B-group',
+ 'score': 0.3064001,
+ 'index': 4,
+ 'word': 'warriors',
+ 'start': 17,
+ 'end': 25},
+ {'entity': 'B-location',
+ 'score': 0.65523505,
+ 'index': 13,
+ 'word': 'san',
+ 'start': 80,
+ 'end': 83},
+ {'entity': 'B-location',
+ 'score': 0.4668663,
+ 'index': 14,
+ 'word': 'francisco',
+ 'start': 84,
+ 'end': 93}]
+```
+
+必要に応じて、`pipeline`の結果を手動で複製することもできます。
+
+
+
+テキストをトークン化して PyTorch テンソルを返します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+```
+
+入力をモデルに渡し、`logits`を返します。
+
+```py
+>>> from transformers import AutoModelForTokenClassification
+
+>>> model = AutoModelForTokenClassification.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+最も高い確率でクラスを取得し、モデルの `id2label` マッピングを使用してそれをテキスト ラベルに変換します。
+
+```py
+>>> predictions = torch.argmax(logits, dim=2)
+>>> predicted_token_class = [model.config.id2label[t.item()] for t in predictions[0]]
+>>> predicted_token_class
+['O',
+ 'O',
+ 'B-location',
+ 'I-location',
+ 'B-group',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'B-location',
+ 'B-location',
+ 'O',
+ 'O']
+```
+
+
+
+
+テキストをトークン化し、TensorFlow テンソルを返します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+```
+
+入力をモデルに渡し、`logits`を返します。
+
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> logits = model(**inputs).logits
+```
+
+最も高い確率でクラスを取得し、モデルの `id2label` マッピングを使用してそれをテキスト ラベルに変換します。
+
+```py
+>>> predicted_token_class_ids = tf.math.argmax(logits, axis=-1)
+>>> predicted_token_class = [model.config.id2label[t] for t in predicted_token_class_ids[0].numpy().tolist()]
+>>> predicted_token_class
+['O',
+ 'O',
+ 'B-location',
+ 'I-location',
+ 'B-group',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'B-location',
+ 'B-location',
+ 'O',
+ 'O']
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/translation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/translation.md
new file mode 100644
index 0000000000000000000000000000000000000000..7fa45eac9cdb682e662bbb976a6be3b94b6c3cd0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/translation.md
@@ -0,0 +1,415 @@
+
+
+# Translation
+
+[[open-in-colab]]
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/translation) を確認することをお勧めします。
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install transformers datasets evaluate sacrebleu
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+## Load OPUS Books dataset
+
+まず、🤗 データセット ライブラリから [OPUS Books](https://huggingface.co/datasets/opus_books) データセットの英語とフランス語のサブセットを読み込みます。
+
+```py
+>>> from datasets import load_dataset
+
+>>> books = load_dataset("opus_books", "en-fr")
+```
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットをトレイン セットとテスト セットに分割します。
+
+
+```py
+>>> books = books["train"].train_test_split(test_size=0.2)
+```
+
+次に、例を見てみましょう。
+
+```py
+>>> books["train"][0]
+{'id': '90560',
+ 'translation': {'en': 'But this lofty plateau measured only a few fathoms, and soon we reentered Our Element.',
+ 'fr': 'Mais ce plateau élevé ne mesurait que quelques toises, et bientôt nous fûmes rentrés dans notre élément.'}}
+```
+
+`translation`: テキストの英語とフランス語の翻訳。
+
+## Preprocess
+
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint)
+```
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint, return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[SacreBLEU](https://huggingface.co/spaces/evaluate-metric/sacrebleu) メトリクスをロードします (🤗 Evaluate [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照してください) ) メトリクスの読み込みと計算方法の詳細については、次を参照してください)。
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("sacrebleu")
+```
+
+次に、予測とラベルを [`~evaluate.EvaluationModule.compute`] に渡して SacreBLEU スコアを計算する関数を作成します。
+```py
+>>> import numpy as np
+
+
+>>> def postprocess_text(preds, labels):
+... preds = [pred.strip() for pred in preds]
+... labels = [[label.strip()] for label in labels]
+
+... return preds, labels
+
+
+>>> def compute_metrics(eval_preds):
+... preds, labels = eval_preds
+... if isinstance(preds, tuple):
+... preds = preds[0]
+... decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
+
+... labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+... decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+... decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
+
+... result = metric.compute(predictions=decoded_preds, references=decoded_labels)
+... result = {"bleu": result["score"]}
+
+... prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in preds]
+... result["gen_len"] = np.mean(prediction_lens)
+... result = {k: round(v, 4) for k, v in result.items()}
+... return result
+```
+これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
+
+## Train
+
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[ここ](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForSeq2SeqLM`] を使用して T5 をロードします。
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM, Seq2SeqTrainingArguments, Seq2SeqTrainer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+この時点で残っているステップは 3 つだけです。
+
+1. [`Seq2SeqTrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`Trainer`] は SacreBLEU メトリクスを評価し、トレーニング チェックポイントを保存します。
+2. トレーニング引数をモデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Seq2SeqTrainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+
+```py
+>>> training_args = Seq2SeqTrainingArguments(
+... output_dir="my_awesome_opus_books_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... weight_decay=0.01,
+... save_total_limit=3,
+... num_train_epochs=2,
+... predict_with_generate=True,
+... fp16=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Seq2SeqTrainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_books["train"],
+... eval_dataset=tokenized_books["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-a-tensorflow-model-with-keras) の基本的なチュートリアルをご覧ください。
+
+
+TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
+
+
+```py
+>>> from transformers import AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+次に、[`TFAutoModelForSeq2SeqLM`] を使用して T5 をロードできます。
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_books["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... tokenized_books["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+トレーニングを開始する前にセットアップする最後の 2 つのことは、予測から SacreBLEU メトリクスを計算し、モデルをハブにプッシュする方法を提供することです。どちらも [Keras コールバック](../main_classes/keras_callbacks) を使用して行われます。
+
+`compute_metrics` 関数を [`~transformers.KerasMetricCallback`] に渡します。
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+[`~transformers.PushToHubCallback`] でモデルとトークナイザーをプッシュする場所を指定します。
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_opus_books_model",
+... tokenizer=tokenizer,
+... )
+```
+
+次に、コールバックをまとめてバンドルします。
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=callbacks)
+```
+
+トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
+
+
+
+
+
+
+翻訳用にモデルを微調整する方法の詳細な例については、対応するドキュメントを参照してください。
+[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation.ipynb)
+または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation-tf.ipynb)。
+
+
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+別の言語に翻訳したいテキストを考え出します。 T5 の場合、作業中のタスクに応じて入力に接頭辞を付ける必要があります。英語からフランス語に翻訳する場合は、以下に示すように入力に接頭辞を付ける必要があります。
+
+```py
+>>> text = "translate English to French: Legumes share resources with nitrogen-fixing bacteria."
+```
+
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して翻訳用の`pipeline`をインスタンス化し、テキストをそれに渡します。
+
+
+```py
+>>> from transformers import pipeline
+
+# Change `xx` to the language of the input and `yy` to the language of the desired output.
+# Examples: "en" for English, "fr" for French, "de" for German, "es" for Spanish, "zh" for Chinese, etc; translation_en_to_fr translates English to French
+# You can view all the lists of languages here - https://huggingface.co/languages
+>>> translator = pipeline("translation_xx_to_yy", model="my_awesome_opus_books_model")
+>>> translator(text)
+[{'translation_text': 'Legumes partagent des ressources avec des bactéries azotantes.'}]
+```
+
+必要に応じて、`pipeline`の結果を手動で複製することもできます。
+
+
+
+
+テキストをトークン化し、`input_ids` を PyTorch テンソルとして返します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_opus_books_model")
+>>> inputs = tokenizer(text, return_tensors="pt").input_ids
+```
+
+[`~generation.GenerationMixin.generate`] メソッドを使用して翻訳を作成します。さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[Text Generation](../main_classes/text_generation) API を確認してください。
+
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("my_awesome_opus_books_model")
+>>> outputs = model.generate(inputs, max_new_tokens=40, do_sample=True, top_k=30, top_p=0.95)
+```
+
+生成されたトークン ID をデコードしてテキストに戻します。
+
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'Les lignées partagent des ressources avec des bactéries enfixant l'azote.'
+```
+
+
+
+
+`input_ids`を TensorFlow テンソルとして返します。 tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_opus_books_model")
+>>> inputs = tokenizer(text, return_tensors="tf").input_ids
+```
+
+[`~transformers.generation_tf_utils.TFGenerationMixin.generate`] メソッドを使用して翻訳を作成します。さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[Text Generation](../main_classes/text_generation) API を確認してください。
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained("my_awesome_opus_books_model")
+>>> outputs = model.generate(inputs, max_new_tokens=40, do_sample=True, top_k=30, top_p=0.95)
+```
+
+生成されたトークン ID をデコードしてテキストに戻します。
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'Les lugumes partagent les ressources avec des bactéries fixatrices d'azote.'
+```
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/video_classification.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/video_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..741356a6f5789e5f447d1c360e835fa917d6bf3f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tasks/video_classification.md
@@ -0,0 +1,498 @@
+
+
+# Video classification
+
+[[open-in-colab]]
+
+
+ビデオ分類は、ビデオ全体にラベルまたはクラスを割り当てるタスクです。ビデオには、各ビデオに 1 つのクラスのみが含まれることが期待されます。ビデオ分類モデルはビデオを入力として受け取り、ビデオがどのクラスに属するかについての予測を返します。これらのモデルを使用して、ビデオの内容を分類できます。ビデオ分類の実際のアプリケーションはアクション/アクティビティ認識であり、フィットネス アプリケーションに役立ちます。また、視覚障害のある人にとって、特に通勤時に役立ちます。
+
+このガイドでは、次の方法を説明します。
+
+1. [UCF101](https://www.crcv.ucf.edu/) のサブセットで [VideoMAE](https://huggingface.co/docs/transformers/main/en/model_doc/videomae) を微調整します。 data/UCF101.php) データセット。
+2. 微調整したモデルを推論に使用します。
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/video-classification) を確認することをお勧めします。
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+```bash
+pip install -q pytorchvideo transformers evaluate
+```
+
+[PyTorchVideo](https://pytorchvideo.org/) (`pytorchvideo` と呼ばれます) を使用してビデオを処理し、準備します。
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load UCF101 dataset
+
+まず、[UCF-101 データセット](https://www.crcv.ucf.edu/data/UCF101.php) のサブセットをロードします。これにより、完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
+
+```py
+>>> from huggingface_hub import hf_hub_download
+
+>>> hf_dataset_identifier = "sayakpaul/ucf101-subset"
+>>> filename = "UCF101_subset.tar.gz"
+>>> file_path = hf_hub_download(repo_id=hf_dataset_identifier, filename=filename, repo_type="dataset")
+```
+
+サブセットをダウンロードした後、圧縮アーカイブを抽出する必要があります。
+
+```py
+>>> import tarfile
+
+>>> with tarfile.open(file_path) as t:
+... t.extractall(".")
+```
+
+大まかに言うと、データセットは次のように構成されています。
+
+```bash
+UCF101_subset/
+ train/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+ val/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+ test/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+```
+
+(`sorted`)された ビデオ パスは次のように表示されます。
+
+
+```bash
+...
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g07_c04.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g07_c06.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g08_c01.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g09_c02.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g09_c06.avi'
+...
+```
+
+同じグループ/シーンに属するビデオ クリップがあり、ビデオ ファイル パスではグループが`g`で示されていることがわかります。たとえば、`v_ApplyEyeMakeup_g07_c04.avi`や`v_ApplyEyeMakeup_g07_c06.avi`などです。
+
+検証と評価の分割では、[データ漏洩](https://www.kaggle.com/code/alexisbcook/data-leakage) を防ぐために、同じグループ/シーンからのビデオ クリップを使用しないでください。このチュートリアルで使用しているサブセットでは、この情報が考慮されています。
+
+次に、データセット内に存在するラベルのセットを取得します。また、モデルを初期化するときに役立つ 2 つの辞書を作成します。
+
+* `label2id`: クラス名を整数にマップします。
+* `id2label`: 整数をクラス名にマッピングします。
+
+
+```py
+>>> class_labels = sorted({str(path).split("/")[2] for path in all_video_file_paths})
+>>> label2id = {label: i for i, label in enumerate(class_labels)}
+>>> id2label = {i: label for label, i in label2id.items()}
+
+>>> print(f"Unique classes: {list(label2id.keys())}.")
+
+# Unique classes: ['ApplyEyeMakeup', 'ApplyLipstick', 'Archery', 'BabyCrawling', 'BalanceBeam', 'BandMarching', 'BaseballPitch', 'Basketball', 'BasketballDunk', 'BenchPress'].
+```
+
+個性的なクラスが10種類あります。トレーニング セットには、クラスごとに 30 個のビデオがあります。
+
+## Load a model to fine-tune
+
+事前トレーニングされたチェックポイントとそれに関連する画像プロセッサからビデオ分類モデルをインスタンス化します。モデルのエンコーダーには事前トレーニングされたパラメーターが付属しており、分類ヘッドはランダムに初期化されます。画像プロセッサは、データセットの前処理パイプラインを作成するときに役立ちます。
+
+```py
+>>> from transformers import VideoMAEImageProcessor, VideoMAEForVideoClassification
+
+>>> model_ckpt = "MCG-NJU/videomae-base"
+>>> image_processor = VideoMAEImageProcessor.from_pretrained(model_ckpt)
+>>> model = VideoMAEForVideoClassification.from_pretrained(
+... model_ckpt,
+... label2id=label2id,
+... id2label=id2label,
+... ignore_mismatched_sizes=True, # provide this in case you're planning to fine-tune an already fine-tuned checkpoint
+... )
+```
+
+モデルのロード中に、次の警告が表示される場合があります。
+
+```bash
+Some weights of the model checkpoint at MCG-NJU/videomae-base were not used when initializing VideoMAEForVideoClassification: [..., 'decoder.decoder_layers.1.attention.output.dense.bias', 'decoder.decoder_layers.2.attention.attention.key.weight']
+- This IS expected if you are initializing VideoMAEForVideoClassification from the checkpoint of a model trained on another task or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).
+- This IS NOT expected if you are initializing VideoMAEForVideoClassification from the checkpoint of a model that you expect to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model).
+Some weights of VideoMAEForVideoClassification were not initialized from the model checkpoint at MCG-NJU/videomae-base and are newly initialized: ['classifier.bias', 'classifier.weight']
+You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.
+```
+
+この警告は、一部の重み (たとえば、`classifier`層の重みとバイアス) を破棄し、他のいくつかの重み (新しい`classifier`層の重みとバイアス) をランダムに初期化していることを示しています。この場合、これは予想されることです。事前にトレーニングされた重みを持たない新しい頭部を追加しているため、推論に使用する前にこのモデルを微調整する必要があるとライブラリが警告します。これはまさに私たちが行おうとしているものです。する。
+
+**注意** [このチェックポイント](https://huggingface.co/MCG-NJU/videomae-base-finetuned-kinetics) は、同様のダウンストリームで微調整されてチェックポイントが取得されたため、このタスクのパフォーマンスが向上することに注意してください。かなりのドメインの重複があるタスク。 `MCG-NJU/videomae-base-finetuned-kinetics` を微調整して取得した [このチェックポイント](https://huggingface.co/sayakpaul/videomae-base-finetuned-kinetics-finetuned-ucf101-subset) を確認できます。 -キネティクス`。
+
+## Prepare the datasets for training
+
+ビデオの前処理には、[PyTorchVideo ライブラリ](https://pytorchvideo.org/) を利用します。まず、必要な依存関係をインポートします。
+
+
+```py
+>>> import pytorchvideo.data
+
+>>> from pytorchvideo.transforms import (
+... ApplyTransformToKey,
+... Normalize,
+... RandomShortSideScale,
+... RemoveKey,
+... ShortSideScale,
+... UniformTemporalSubsample,
+... )
+
+>>> from torchvision.transforms import (
+... Compose,
+... Lambda,
+... RandomCrop,
+... RandomHorizontalFlip,
+... Resize,
+... )
+```
+
+トレーニング データセットの変換には、均一な時間サブサンプリング、ピクセル正規化、ランダム クロッピング、およびランダムな水平反転を組み合わせて使用します。検証および評価のデータセット変換では、ランダムなトリミングと水平反転を除き、同じ変換チェーンを維持します。これらの変換の詳細については、[PyTorchVideo の公式ドキュメント](https://pytorchvideo.org) を参照してください。
+
+事前トレーニングされたモデルに関連付けられた`image_processor`を使用して、次の情報を取得します。
+
+* ビデオ フレームのピクセルが正規化される画像の平均値と標準偏差。
+* ビデオ フレームのサイズが変更される空間解像度。
+
+まず、いくつかの定数を定義します。
+
+```py
+>>> mean = image_processor.image_mean
+>>> std = image_processor.image_std
+>>> if "shortest_edge" in image_processor.size:
+... height = width = image_processor.size["shortest_edge"]
+>>> else:
+... height = image_processor.size["height"]
+... width = image_processor.size["width"]
+>>> resize_to = (height, width)
+
+>>> num_frames_to_sample = model.config.num_frames
+>>> sample_rate = 4
+>>> fps = 30
+>>> clip_duration = num_frames_to_sample * sample_rate / fps
+```
+
+次に、データセット固有の変換とデータセットをそれぞれ定義します。トレーニングセットから始めます:
+
+
+```py
+>>> train_transform = Compose(
+... [
+... ApplyTransformToKey(
+... key="video",
+... transform=Compose(
+... [
+... UniformTemporalSubsample(num_frames_to_sample),
+... Lambda(lambda x: x / 255.0),
+... Normalize(mean, std),
+... RandomShortSideScale(min_size=256, max_size=320),
+... RandomCrop(resize_to),
+... RandomHorizontalFlip(p=0.5),
+... ]
+... ),
+... ),
+... ]
+... )
+
+>>> train_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "train"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("random", clip_duration),
+... decode_audio=False,
+... transform=train_transform,
+... )
+```
+
+同じ一連のワークフローを検証セットと評価セットに適用できます。
+
+
+```py
+>>> val_transform = Compose(
+... [
+... ApplyTransformToKey(
+... key="video",
+... transform=Compose(
+... [
+... UniformTemporalSubsample(num_frames_to_sample),
+... Lambda(lambda x: x / 255.0),
+... Normalize(mean, std),
+... Resize(resize_to),
+... ]
+... ),
+... ),
+... ]
+... )
+
+>>> val_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "val"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("uniform", clip_duration),
+... decode_audio=False,
+... transform=val_transform,
+... )
+
+>>> test_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "test"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("uniform", clip_duration),
+... decode_audio=False,
+... transform=val_transform,
+... )
+```
+
+**注意**: 上記のデータセット パイプラインは、[公式 PyTorchVideo サンプル](https://pytorchvideo.org/docs/tutorial_classification#dataset) から取得したものです。 [`pytorchvideo.data.Ucf101()`](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html#pytorchvideo.data.Ucf101) 関数を使用しています。 UCF-101 データセット。内部では、[`pytorchvideo.data.labeled_video_dataset.LabeledVideoDataset`](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html#pytorchvideo.data.LabeledVideoDataset) オブジェクトを返します。 `LabeledVideoDataset` クラスは、PyTorchVideo データセット内のすべてのビデオの基本クラスです。したがって、PyTorchVideo で既製でサポートされていないカスタム データセットを使用したい場合は、それに応じて `LabeledVideoDataset` クラスを拡張できます。詳細については、`data`API [ドキュメント](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html)を参照してください。また、データセットが同様の構造 (上に示したもの) に従っている場合は、`pytorchvideo.data.Ucf101()` を使用すると問題なく動作するはずです。
+
+`num_videos` 引数にアクセスすると、データセット内のビデオの数を知ることができます。
+
+
+
+```py
+>>> print(train_dataset.num_videos, val_dataset.num_videos, test_dataset.num_videos)
+# (300, 30, 75)
+```
+
+## Visualize the preprocessed video for better debugging
+
+```py
+>>> import imageio
+>>> import numpy as np
+>>> from IPython.display import Image
+
+>>> def unnormalize_img(img):
+... """Un-normalizes the image pixels."""
+... img = (img * std) + mean
+... img = (img * 255).astype("uint8")
+... return img.clip(0, 255)
+
+>>> def create_gif(video_tensor, filename="sample.gif"):
+... """Prepares a GIF from a video tensor.
+...
+... The video tensor is expected to have the following shape:
+... (num_frames, num_channels, height, width).
+... """
+... frames = []
+... for video_frame in video_tensor:
+... frame_unnormalized = unnormalize_img(video_frame.permute(1, 2, 0).numpy())
+... frames.append(frame_unnormalized)
+... kargs = {"duration": 0.25}
+... imageio.mimsave(filename, frames, "GIF", **kargs)
+... return filename
+
+>>> def display_gif(video_tensor, gif_name="sample.gif"):
+... """Prepares and displays a GIF from a video tensor."""
+... video_tensor = video_tensor.permute(1, 0, 2, 3)
+... gif_filename = create_gif(video_tensor, gif_name)
+... return Image(filename=gif_filename)
+
+>>> sample_video = next(iter(train_dataset))
+>>> video_tensor = sample_video["video"]
+>>> display_gif(video_tensor)
+```
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+さらに進む前に、元のTransformerアーキテクチャの基本的な知識を持つと良いです。エンコーダ、デコーダ、および注意力がどのように動作するかを知っておくと、異なるTransformerモデルがどのように動作するかを理解するのに役立ちます。始めているか、リフレッシュが必要な場合は、詳細な情報については当社の[コース](https://huggingface.co/course/chapter1/4?fw=pt)をチェックしてください!
+
+
+
+## Speech and audio
+
+[Wav2Vec2](model_doc/wav2vec2)は、未ラベルの音声データで事前トレーニングされ、オーディオ分類および自動音声認識のラベル付きデータでファインチューンされた自己教師モデルです。
+
+
+
+
+
+サードアプローチでは、Transformerと畳み込みを組み合わせたものもあります(例:[Convolutional Vision Transformer](model_doc/cvt)または[LeViT](model_doc/levit))。これらについては議論しませんが、これらはここで調べる2つのアプローチを組み合わせています。
+
+
+
+ViTとConvNeXTは画像分類によく使用されますが、オブジェクト検出、セグメンテーション、深度推定などの他のビジョンタスクに対しては、DETR、Mask2Former、GLPNなどが適しています。
+
+### Image classification
+
+ViTとConvNeXTの両方を画像分類に使用できます。主な違いは、ViTが注意メカニズムを使用し、ConvNeXTが畳み込みを使用することです。
+
+#### Transformer
+
+[ViT](model_doc/vit)は畳み込みを完全にTransformerアーキテクチャで置き換えます。元のTransformerに精通している場合、ViTの理解は既にほとんど完了しています。
+
+
+
+
+
+このセクションでは畳み込みについて簡単に説明していますが、画像の形状とサイズがどのように変化するかを事前に理解していると役立ちます。畳み込みに慣れていない場合は、fastaiの書籍から[Convolution Neural Networks chapter](https://github.com/fastai/fastbook/blob/master/13_convolutions.ipynb)をチェックしてみてください!
+
+
+
+[ConvNeXT](model_doc/convnext)は、性能を向上させるために新しいモダンなネットワーク設計を採用したCNNアーキテクチャです。ただし、畳み込みはモデルの中核にまだあります。高レベルから見た場合、[畳み込み(convolution)](glossary#convolution)は、小さな行列(*カーネル*)が画像のピクセルの小さなウィンドウに乗算される操作です。それは特定のテクスチャや線の曲率などの特徴を計算します。その後、次のピクセルのウィンドウに移動します。畳み込みが移動する距離は*ストライド*として知られています。
+
+
+
+
[Convolution Arithmetic for Deep Learning](https://arxiv.org/abs/1603.07285) からの基本的なパディングやストライドのない畳み込み。
+
+この出力を別の畳み込み層に供給し、各連続した層ごとに、ネットワークはホットドッグやロケットのようなより複雑で抽象的なものを学習します。畳み込み層の間には、特徴の次元を削減し、特徴の位置の変動に対してモデルをより堅牢にするためにプーリング層を追加するのが一般的です。
+
+
+
+
+
+
+
+
+
+
+
+💡 注意してください。一度事前トレーニングが完了したBERTを使用してさまざまなタスクに簡単に適用できることに注目してください。必要なのは、事前トレーニング済みモデルに特定のヘッドを追加して、隠れた状態を所望の出力に変換することだけです!
+
+
+
+### Text generation
+
+[GPT-2](model_doc/gpt2)は大量のテキストで事前トレーニングされたデコーダー専用モデルです。プロンプトを与えると説得力のあるテキストを生成し、明示的にトレーニングされていないにもかかわらず、質問応答などの他のNLPタスクも完了できます。
+
+
+
+
+
+テキスト生成に関する詳細は、[テキスト生成戦略](generation_strategies)ガイドをチェックしてみてください!
+
+
+
+
+### Summarization
+
+[BART](model_doc/bart) や [T5](model_doc/t5) のようなエンコーダーデコーダーモデルは、要約タスクのシーケンス・トゥ・シーケンス・パターンに設計されています。このセクションでは、BARTの動作方法を説明し、最後にT5の微調整を試すことができます。
+
+
+
+
+
+テキスト生成に関する詳細は、[テキスト生成戦略](generation_strategies)ガイドをチェックしてみてください!
+
+
+
+### Translation
+
+翻訳は、もう一つのシーケンス・トゥ・シーケンス・タスクの例であり、[BART](model_doc/bart) や [T5](model_doc/t5) のようなエンコーダーデコーダーモデルを使用して実行できます。このセクションでは、BARTの動作方法を説明し、最後にT5の微調整を試すことができます。
+
+BARTは、ソース言語をターゲット言語にデコードできるようにするために、別個にランダムに初期化されたエンコーダーを追加することで翻訳に適応します。この新しいエンコーダーの埋め込みは、元の単語埋め込みの代わりに事前トレーニング済みのエンコーダーに渡されます。ソースエンコーダーは、モデルの出力からのクロスエントロピー損失を用いてソースエンコーダー、位置エンベディング、および入力エンベディングを更新することによって訓練されます。この最初のステップではモデルパラメータが固定され、すべてのモデルパラメータが2番目のステップで一緒に訓練されます。
+
+その後、翻訳のために多言語版のmBARTが登場し、多言語で事前トレーニングされたモデルとして利用可能です。
+
+翻訳を試す準備はできましたか?T5を微調整して推論に使用する方法を学ぶために、完全な[翻訳ガイド](tasks/summarization)をご覧ください!
+
+
+
+テキスト生成に関する詳細は、[テキスト生成戦略](generation_strategies)ガイドをチェックしてみてください!
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/testing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/testing.md
new file mode 100644
index 0000000000000000000000000000000000000000..8831d48a3bdaff4739b8425828d15fffbdce2b6a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/testing.md
@@ -0,0 +1,1213 @@
+
+
+# Testing
+
+🤗 Transformersモデルがどのようにテストされ、新しいテストを書いて既存のテストを改善できるかを見てみましょう。
+
+このリポジトリには2つのテストスイートがあります:
+
+1. `tests` -- 一般的なAPI用のテスト
+2. `examples` -- APIの一部ではないさまざまなアプリケーション用のテスト
+
+## How transformers are tested
+
+1. PRが提出されると、9つのCircleCiジョブでテストされます。PRへの新しいコミットごとに再テストされます。これらのジョブは、[この設定ファイル](https://github.com/huggingface/transformers/tree/main/.circleci/config.yml)で定義されており、必要な場合は同じ環境を自分のマシンで再現できます。
+
+ これらのCIジョブは `@slow` テストを実行しません。
+
+2. [GitHub Actions](https://github.com/huggingface/transformers/actions)によって実行される3つのジョブがあります:
+
+ - [torch hub integration](https://github.com/huggingface/transformers/tree/main/.github/workflows/github-torch-hub.yml): torch hubの統合が動作するかどうかを確認します。
+
+ - [self-hosted (push)](https://github.com/huggingface/transformers/tree/main/.github/workflows/self-push.yml): `main` にコミットが行われた場合に、GPUで高速テストを実行します。このジョブは、`main` でのコミットが以下のフォルダーのコードを更新した場合にのみ実行されます:`src`、`tests`、`.github`(追加されたモデルカード、ノートブックなどの実行を防ぐため)。
+
+ - [self-hosted runner](https://github.com/huggingface/transformers/tree/main/.github/workflows/self-scheduled.yml): GPUで `tests` と `examples` の通常のテストと遅いテストを実行します。
+
+```bash
+RUN_SLOW=1 pytest tests/
+RUN_SLOW=1 pytest examples/
+```
+ 結果は[here](https://github.com/huggingface/transformers/actions)で観察できます。
+
+## Running tests
+
+
+
+### Choosing which tests to run
+
+このドキュメントは、テストを実行する方法の多くの詳細について説明しています。すべてを読んだ後でも、さらに詳細が必要な場合は、[こちら](https://docs.pytest.org/en/latest/usage.html)で見つけることができます。
+
+以下は、テストを実行するためのいくつかの最も便利な方法です。
+
+すべて実行します:
+```console
+pytest
+```
+
+または:
+```bash
+make test
+```
+
+
+後者は次のように定義されることに注意してください。
+
+```bash
+python -m pytest -n auto --dist=loadfile -s -v ./tests/
+```
+
+以下は、pytestに渡す設定情報です。
+
+- テストプロセスをCPUコアの数と同じだけ実行するように指示します。ただし、RAMが十分でない場合は注意が必要です。
+- 同じファイルからのすべてのテストは、同じテストプロセスで実行されるようにします。
+- 出力のキャプチャを行いません。
+- 冗長モードで実行します。
+
+
+### Getting the list of all tests
+
+テストスイートのすべてのテスト:
+
+```bash
+pytest --collect-only -q
+```
+
+指定されたテスト ファイルのすべてのテスト:
+
+```bash
+pytest tests/test_optimization.py --collect-only -q
+```
+
+### Run a specific test module
+
+個別のテスト モジュールを実行するには:
+
+```bash
+pytest tests/utils/test_logging.py
+```
+
+### Run specific tests
+
+ほとんどのテストでunittestが使用されているため、特定のサブテストを実行するには、それらのテストを含むunittestクラスの名前を知っている必要があります。例えば、それは次のようになるかもしれません:
+
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest::test_adam_w
+```
+
+テストの実行方法:
+
+テストファイル: `tests/test_optimization.py`
+クラス名: `OptimizationTest`
+テスト関数の名前: `test_adam_w`
+
+ファイルに複数のクラスが含まれている場合は、特定のクラスのテストのみを実行することを選択できます。例えば:
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest
+```
+
+テストクラス内のすべてのテストを実行します。
+
+前述の通り、`OptimizationTest` クラスに含まれるテストを実行するには、次のコマンドを実行できます:
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest --collect-only -q
+```
+
+キーワード式を使用してテストを実行できます。
+
+名前に `adam` が含まれるテストのみを実行するには:
+
+```bash
+pytest -k adam tests/test_optimization.py
+```
+
+`and`および`or`は、すべてのキーワードが一致するか、いずれかを示すために使用できます。`not`は否定するために使用できます。
+
+`adam`という名前を含むテストを除いてすべてのテストを実行するには:
+
+```bash
+pytest -k "not adam" tests/test_optimization.py
+```
+
+
+以下は、提供されたテキストの日本語訳です。
+
+```bash
+pytest -k "ada and not adam" tests/test_optimization.py
+```
+
+たとえば、`test_adafactor`と`test_adam_w`の両方を実行するには、以下のコマンドを使用できます:
+
+```bash
+pytest -k "test_adam_w or test_adam_w" tests/test_optimization.py
+```
+
+注意: ここでは、`or` を使用しています。キーワードのいずれか一つが一致すれば、両方を含めるためです。
+
+両方のパターンを含むテストのみを含めたい場合は、`and` を使用してください。
+
+```bash
+pytest -k "test and ada" tests/test_optimization.py
+```
+
+### Run `accelerate` tests
+
+時々、モデルに対して `accelerate` テストを実行する必要があります。たとえば、`OPT` 実行に対してこれらのテストを実行したい場合、コマンドに `-m accelerate_tests` を追加するだけで済みます:
+
+```bash
+RUN_SLOW=1 pytest -m accelerate_tests tests/models/opt/test_modeling_opt.py
+```
+
+### Run documentation tests
+
+ドキュメンテーションの例が正しいかどうかをテストするには、`doctests` が合格しているかを確認する必要があります。
+例として、[`WhisperModel.forward` のドックストリング](https://github.com/huggingface/transformers/blob/main/src/transformers/models/whisper/modeling_whisper.py#L1017-L1035)を使用しましょう。
+
+
+```python
+r"""
+Returns:
+
+Example:
+ ```python
+ >>> import torch
+ >>> from transformers import WhisperModel, WhisperFeatureExtractor
+ >>> from datasets import load_dataset
+
+ >>> model = WhisperModel.from_pretrained("openai/whisper-base")
+ >>> feature_extractor = WhisperFeatureExtractor.from_pretrained("openai/whisper-base")
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> inputs = feature_extractor(ds[0]["audio"]["array"], return_tensors="pt")
+ >>> input_features = inputs.input_features
+ >>> decoder_input_ids = torch.tensor([[1, 1]]) * model.config.decoder_start_token_id
+ >>> last_hidden_state = model(input_features, decoder_input_ids=decoder_input_ids).last_hidden_state
+ >>> list(last_hidden_state.shape)
+ [1, 2, 512]
+ ```"""
+
+```
+
+指定したファイル内のすべてのドックストリング例を自動的にテストするために、以下の行を実行してください:
+
+```bash
+pytest --doctest-modules
+```
+
+ファイルにマークダウン拡張子がある場合は、`--doctest-glob="*.md"`引数を追加する必要があります。
+
+
+### Run only modified tests
+
+[pytest-picked](https://github.com/anapaulagomes/pytest-picked)を使用すると、未ステージングのファイルまたは現在のブランチ(Gitに従って)に関連するテストを実行できます。これは、変更内容に関連するテストのみ実行されるため、変更が何も壊れていないことを迅速に確認する素晴らしい方法です。変更されていないファイルに関連するテストは実行されません。
+
+```bash
+pip install pytest-picked
+```
+
+```bash
+pytest --picked
+```
+
+すべてのテストは、変更されたがまだコミットされていないファイルとフォルダから実行されます。
+
+### Automatically rerun failed tests on source modification
+
+[pytest-xdist](https://github.com/pytest-dev/pytest-xdist)は、非常に便利な機能を提供しており、すべての失敗したテストを検出し、ファイルを修正する間にそれらの失敗したテストを連続して再実行することができます。そのため、修正を行った後にpytestを再起動する必要がありません。すべてのテストが合格するまで繰り返され、その後再度フルランが実行されます。
+
+
+```bash
+pip install pytest-xdist
+```
+
+モードに入るには: `pytest -f`または`pytest --looponfail`
+
+ファイルの変更は、`looponfailroots`ルートディレクトリとその内容全体(再帰的に)を見て検出されます。この値のデフォルトが機能しない場合、`setup.cfg`で設定オプションを変更してプロジェクト内で変更できます。
+
+
+```ini
+[tool:pytest]
+looponfailroots = transformers tests
+```
+
+または `pytest.ini`/`tox.ini` ファイル:
+
+```ini
+[pytest]
+looponfailroots = transformers tests
+```
+
+ファイルの変更を探すことは、iniファイルのディレクトリを基準にして指定されたディレクトリ内でのみ行われます。
+
+[pytest-watch](https://github.com/joeyespo/pytest-watch) は、この機能の代替実装です。
+
+### Skip a test module
+
+特定のテストモジュールを除外してすべてのテストモジュールを実行したい場合、実行するテストの明示的なリストを指定することができます。例えば、`test_modeling_*.py` テストを除外してすべてを実行するには次のようにします:
+
+```bash
+pytest *ls -1 tests/*py | grep -v test_modeling*
+```
+
+### Clearing state
+
+CIビルドおよび速度に対する隔離が重要な場合(キャッシュに対して)、キャッシュをクリアする必要があります:
+
+```bash
+pytest --cache-clear tests
+```
+
+### Running tests in parallel
+
+前述のように、`make test` は `pytest-xdist` プラグインを介してテストを並列実行します(`-n X` 引数、例: `-n 2` で2つの並列ジョブを実行)。
+
+`pytest-xdist` の `--dist=` オプションを使用すると、テストがどのようにグループ化されるかを制御できます。`--dist=loadfile` は同じファイルにあるテストを同じプロセスに配置します。
+
+テストの実行順序が異なり予測不可能であるため、`pytest-xdist` を使用してテストスイートを実行すると失敗が発生する場合(つまり、いくつかの未検出の連動テストがある場合)、[pytest-replay](https://github.com/ESSS/pytest-replay) を使用してテストを同じ順序で再生し、その後、失敗するシーケンスを最小限にするのに役立ちます。
+
+### Test order and repetition
+
+潜在的な相互依存性や状態に関連するバグ(ティアダウン)を検出するために、テストを複数回、連続して、ランダムに、またはセットで繰り返すことは有用です。そして、単純な複数回の繰り返しは、DLのランダム性によって明らかになるいくつかの問題を検出するのに役立ちます。
+
+#### Repeat tests
+
+- [pytest-flakefinder](https://github.com/dropbox/pytest-flakefinder):
+
+```bash
+pip install pytest-flakefinder
+```
+
+そして、すべてのテストを複数回実行します (デフォルトでは 50 回)。
+
+```bash
+pytest --flake-finder --flake-runs=5 tests/test_failing_test.py
+```
+
+
+
+このプラグインは、`pytest-xdist` の `-n` フラグでは動作しません。
+
+
+
+
+
+
+別のプラグイン `pytest-repeat` もありますが、これは `unittest` では動作しません。
+
+
+
+#### Run tests in a random order
+
+```bash
+pip install pytest-random-order
+```
+
+重要: `pytest-random-order` が存在すると、テストは自動的にランダム化されます。設定の変更や変更は必要ありません。
+コマンドラインオプションは必須です。
+
+前に説明したように、これにより、結合されたテスト (1 つのテストの状態が別のテストの状態に影響を与える) の検出が可能になります。いつ
+`pytest-random-order` がインストールされていると、そのセッションに使用されたランダム シードが出力されます。例:
+
+
+```bash
+pytest tests
+[...]
+Using --random-order-bucket=module
+Using --random-order-seed=573663
+```
+
+そのため、指定された特定のシーケンスが失敗した場合、その正確なシードを追加することでそれを再現できます。例:
+
+```bash
+pytest --random-order-seed=573663
+[...]
+Using --random-order-bucket=module
+Using --random-order-seed=573663
+```
+
+特定のテストのリストを使用しない場合、またはまったくリストを使用しない場合、同じテストの正確な順序を再現します。テストのリストを手動で絞り込み始めると、シードに依存せず、テストが失敗した正確な順序で手動でリストを指定する必要があります。これには、`--random-order-bucket=none` を使用してランダム化を無効にするようpytestに指示する必要があります。例えば、次のようにします:
+
+
+```bash
+pytest --random-order-bucket=none tests/test_a.py tests/test_c.py tests/test_b.py
+```
+
+すべてのテストのシャッフルを無効にするには:
+
+```bash
+pytest --random-order-bucket=none
+```
+
+デフォルトでは、`--random-order-bucket=module` が暗黙的に適用され、モジュールレベルでファイルをシャッフルします。また、`class`、`package`、`global`、および`none` レベルでシャッフルすることもできます。詳細については、その[ドキュメンテーション](https://github.com/jbasko/pytest-random-order)を参照してください。
+
+別のランダム化の代替手段は、[`pytest-randomly`](https://github.com/pytest-dev/pytest-randomly) です。このモジュールは非常に似た機能/インターフェースを持っていますが、`pytest-random-order` で利用可能なバケットモードを持っていません。インストール後に自動的に有効になるという同じ問題があります。
+
+### Look and feel variations
+
+#### pytest-sugar
+
+[pytest-sugar](https://github.com/Frozenball/pytest-sugar) は、外観と操作性を向上させ、プログレスバーを追加し、即座に失敗したテストとアサーションを表示するプラグインです。インストール後に自動的にアクティブ化されます。
+
+```bash
+pip install pytest-sugar
+```
+
+
+これを使用せずにテストを実行するには、次を実行します。
+
+```bash
+pytest -p no:sugar
+```
+
+またはアンインストールします。
+
+#### Report each sub-test name and its progress
+
+`pytest` による単一またはグループのテストの場合 (`pip install pytest-pspec` の後):
+
+
+```bash
+pytest --pspec tests/test_optimization.py
+```
+
+
+#### Instantly shows failed tests
+
+[pytest-instafail](https://github.com/pytest-dev/pytest-instafail) では、失敗とエラーが即座に表示されます。
+テストセッションが終了するまで待機します。
+
+```bash
+pip install pytest-instafail
+```
+
+```bash
+pytest --instafail
+```
+
+### To GPU or not to GPU
+
+GPU が有効な設定で、CPU のみモードでテストするには、`CUDA_VISIBLE_DEVICES=""`を追加します。
+
+```bash
+CUDA_VISIBLE_DEVICES="" pytest tests/utils/test_logging.py
+```
+
+
+または、複数の GPU がある場合は、`pytest` でどれを使用するかを指定できます。たとえば、
+2 番目の GPU GPU `0` と `1` がある場合は、次を実行できます。
+
+```bash
+CUDA_VISIBLE_DEVICES="1" pytest tests/utils/test_logging.py
+```
+
+これは、異なるGPUで異なるタスクを実行したい場合に便利です。
+
+一部のテストはCPUのみで実行する必要があり、他のテストはCPU、GPU、またはTPUで実行する必要があり、また別のテストは複数のGPUで実行する必要があります。次のスキップデコレーターは、テストのCPU/GPU/TPUに関する要件を設定するために使用されます:
+
+- `require_torch` - このテストはtorchの下でのみ実行されます。
+- `require_torch_gpu` - `require_torch` に加えて、少なくとも1つのGPUが必要です。
+- `require_torch_multi_gpu` - `require_torch` に加えて、少なくとも2つのGPUが必要です。
+- `require_torch_non_multi_gpu` - `require_torch` に加えて、0または1つのGPUが必要です。
+- `require_torch_up_to_2_gpus` - `require_torch` に加えて、0、1、または2つのGPUが必要です。
+- `require_torch_xla` - `require_torch` に加えて、少なくとも1つのTPUが必要です。
+
+以下の表にGPUの要件を示します:
+
+| n gpus | decorator |
+|--------+--------------------------------|
+| `>= 0` | `@require_torch` |
+| `>= 1` | `@require_torch_gpu` |
+| `>= 2` | `@require_torch_multi_gpu` |
+| `< 2` | `@require_torch_non_multi_gpu` |
+| `< 3` | `@require_torch_up_to_2_gpus` |
+
+
+たとえば、使用可能な GPU が 2 つ以上あり、pytorch がインストールされている場合にのみ実行する必要があるテストを次に示します。
+
+
+```python no-style
+@require_torch_multi_gpu
+def test_example_with_multi_gpu():
+```
+
+テストに `tensorflow` が必要な場合は、`require_tf` デコレータを使用します。例えば:
+
+```python no-style
+@require_tf
+def test_tf_thing_with_tensorflow():
+```
+
+これらのデコレータは積み重ねることができます。たとえば、テストが遅く、pytorch で少なくとも 1 つの GPU が必要な場合は、次のようになります。
+設定方法:
+
+```python no-style
+@require_torch_gpu
+@slow
+def test_example_slow_on_gpu():
+```
+
+`@parametrized` のような一部のデコレータはテスト名を書き換えるため、`@require_*` スキップ デコレータをリストする必要があります。
+最後にそれらが正しく動作するようにします。正しい使用例は次のとおりです
+
+```python no-style
+@parameterized.expand(...)
+@require_torch_multi_gpu
+def test_integration_foo():
+```
+
+この順序の問題は `@pytest.mark.parametrize` には存在しません。最初または最後に配置しても、それでも問題は解決されます。
+仕事。ただし、それは非単体テストでのみ機能します。
+
+内部テスト:
+
+- 利用可能な GPU の数:
+
+```python
+from transformers.testing_utils import get_gpu_count
+
+n_gpu = get_gpu_count() # works with torch and tf
+```
+
+### Testing with a specific PyTorch backend or device
+
+特定のtorchデバイスでテストスイートを実行するには、`TRANSFORMERS_TEST_DEVICE="$device"` を追加します。ここで `$device` は対象のバックエンドです。例えば、CPUでテストするには以下のようにします:
+
+```bash
+TRANSFORMERS_TEST_DEVICE="cpu" pytest tests/utils/test_logging.py
+```
+
+この変数は、`mps`などのカスタムまたはあまり一般的ではない PyTorch バックエンドをテストするのに役立ちます。また、特定の GPU をターゲットにしたり、CPU 専用モードでテストしたりすることで、`CUDA_VISIBLE_DEVICES`と同じ効果を達成するために使用することもできます。
+
+特定のデバイスでは、初めて「torch」をインポートした後、追加のインポートが必要になります。これは、環境変数 `TRANSFORMERS_TEST_BACKEND` を使用して指定できます。
+
+```bash
+TRANSFORMERS_TEST_BACKEND="torch_npu" pytest tests/utils/test_logging.py
+```
+
+### Distributed training
+
+`pytest` は直接的に分散トレーニングを処理することはできません。試みると、サブプロセスは正しい処理を行わず、自分自身が `pytest` であると思い込んでテストスイートをループで実行し続けます。ただし、通常のプロセスを生成し、それから複数のワーカーを生成し、IOパイプを管理するプロセスを生成すれば機能します。
+
+これを使用するいくつかのテストがあります:
+
+- [test_trainer_distributed.py](https://github.com/huggingface/transformers/tree/main/tests/trainer/test_trainer_distributed.py)
+- [test_deepspeed.py](https://github.com/huggingface/transformers/tree/main/tests/deepspeed/test_deepspeed.py)
+
+実行ポイントにすぐに移動するには、これらのテスト内で `execute_subprocess_async` 呼び出しを検索してください。
+
+これらのテストを実行するには、少なくとも2つのGPUが必要です:
+
+```bash
+CUDA_VISIBLE_DEVICES=0,1 RUN_SLOW=1 pytest -sv tests/test_trainer_distributed.py
+```
+
+### Output capture
+
+テストの実行中に、`stdout` および `stderr` に送信された出力はキャプチャされます。テストまたはセットアップメソッドが失敗した場合、通常、それに対応するキャプチャされた出力が失敗のトレースバックと共に表示されます。
+
+出力のキャプチャを無効にし、`stdout` と `stderr` を通常通りに取得するには、`-s` または `--capture=no` を使用してください:
+
+これらのテストを実行するには少なくとも2つのGPUが必要です:
+
+```bash
+pytest -s tests/utils/test_logging.py
+```
+
+テスト結果を JUnit 形式の出力に送信するには:
+
+```bash
+py.test tests --junitxml=result.xml
+```
+
+### Color control
+
+色を持たないようにする(例:黄色のテキストを白い背景に表示すると読みにくいです):
+
+
+```bash
+pytest --color=no tests/utils/test_logging.py
+```
+
+### Sending test report to online pastebin service
+
+テスト失敗ごとに URL を作成します。
+
+
+```bash
+pytest --pastebin=failed tests/utils/test_logging.py
+```
+
+これにより、テスト実行情報がリモートのPasteサービスに送信され、各エラーに対してURLが提供されます。通常通りテストを選択するか、たとえば特定のエラーのみを送信したい場合は `-x` を追加で指定できます。
+
+テストセッション全体のログに対するURLを作成する方法:
+
+
+```bash
+pytest --pastebin=all tests/utils/test_logging.py
+```
+
+## Writing tests
+
+🤗 transformersのテストは `unittest` を基にしていますが、 `pytest` で実行されるため、ほとんどの場合、両方のシステムの機能を使用できます。
+
+[こちら](https://docs.pytest.org/en/stable/unittest.html)でサポートされている機能を読むことができますが、重要なことは、ほとんどの `pytest` のフィクスチャが動作しないことです。パラメータ化も同様ですが、似たような方法で動作する `parameterized` モジュールを使用しています。
+
+### Parametrization
+
+同じテストを異なる引数で複数回実行する必要があることがよくあります。これはテスト内部から行うこともできますが、その場合、そのテストを単一の引数セットで実行する方法はありません。
+
+
+```python
+# test_this1.py
+import unittest
+from parameterized import parameterized
+
+
+class TestMathUnitTest(unittest.TestCase):
+ @parameterized.expand(
+ [
+ ("negative", -1.5, -2.0),
+ ("integer", 1, 1.0),
+ ("large fraction", 1.6, 1),
+ ]
+ )
+ def test_floor(self, name, input, expected):
+ assert_equal(math.floor(input), expected)
+```
+
+デフォルトでは、このテストは3回実行され、それぞれの実行で `test_floor` の最後の3つの引数がパラメータリストの対応する引数に割り当てられます。
+
+そして、`negative` と `integer` パラメータのセットのみを実行することもできます:
+
+```bash
+pytest -k "negative and integer" tests/test_mytest.py
+```
+
+または、`Negative`のサブテストを除くすべての場合、次のようになります。
+
+```bash
+pytest -k "not negative" tests/test_mytest.py
+```
+
+`-k` フィルターを使用することに加えて、各サブテストの正確な名前を調べ、その正確な名前を使用して任意のサブテストまたはすべてのサブテストを実行することができます。
+
+
+```bash
+pytest test_this1.py --collect-only -q
+```
+
+すると次のものがリストされます:
+
+```bash
+test_this1.py::TestMathUnitTest::test_floor_0_negative
+test_this1.py::TestMathUnitTest::test_floor_1_integer
+test_this1.py::TestMathUnitTest::test_floor_2_large_fraction
+```
+
+
+したがって、2 つの特定のサブテストのみを実行できるようになりました。
+
+```bash
+pytest test_this1.py::TestMathUnitTest::test_floor_0_negative test_this1.py::TestMathUnitTest::test_floor_1_integer
+```
+
+`transformers`の開発者依存関係にすでに含まれているモジュール[parameterized](https://pypi.org/project/parameterized/) は、`unittests` と `pytest` テストの両方で機能します。
+
+ただし、テストが `unittest` でない場合、`pytest.mark.parametrize` を使用することができます(または既存のテストのいくつかで、主に `examples` の下で使用されているのを見ることができます)。
+
+次に、同じ例を示しますが、今度は `pytest` の `parametrize` マーカーを使用しています:
+
+
+```python
+# test_this2.py
+import pytest
+
+
+@pytest.mark.parametrize(
+ "name, input, expected",
+ [
+ ("negative", -1.5, -2.0),
+ ("integer", 1, 1.0),
+ ("large fraction", 1.6, 1),
+ ],
+)
+def test_floor(name, input, expected):
+ assert_equal(math.floor(input), expected)
+```
+
+`parameterized` と同様に、`pytest.mark.parametrize` を使用すると、`-k` フィルタが役立たない場合でも、サブテストの実行を細かく制御できます。ただし、このパラメータ化関数はサブテストの名前をわずかに異なるものにします。以下にその例を示します:
+
+
+```bash
+pytest test_this2.py --collect-only -q
+```
+
+すると次のものがリストされます:
+
+```bash
+test_this2.py::test_floor[integer-1-1.0]
+test_this2.py::test_floor[negative--1.5--2.0]
+test_this2.py::test_floor[large fraction-1.6-1]
+```
+
+これで、特定のテストのみを実行できるようになりました。
+
+```bash
+pytest test_this2.py::test_floor[negative--1.5--2.0] test_this2.py::test_floor[integer-1-1.0]
+```
+
+前の例と同様に。
+
+### Files and directories
+
+テストの中で、現在のテストファイルからの相対位置を知る必要があることがよくあります。しかし、これは簡単なことではありません。なぜなら、テストは複数のディレクトリから呼び出されるか、異なる深さのサブディレクトリに存在することがあるからです。`transformers.test_utils.TestCasePlus` というヘルパークラスは、すべての基本パスを整理し、簡単にアクセスできるようにすることで、この問題を解決します。
+
+- `pathlib` オブジェクト(すべて完全に解決されたもの):
+
+ - `test_file_path` - 現在のテストファイルのパス、つまり `__file__`
+ - `test_file_dir` - 現在のテストファイルを含むディレクトリ
+ - `tests_dir` - `tests` テストスイートのディレクトリ
+ - `examples_dir` - `examples` テストスイートのディレクトリ
+ - `repo_root_dir` - リポジトリのディレクトリ
+ - `src_dir` - `transformers` サブディレクトリが存在する場所
+
+- パスの文字列表現――上記と同じですが、これらは `pathlib` オブジェクトではなく文字列としてパスを返します:
+
+ - `test_file_path_str`
+ - `test_file_dir_str`
+ - `tests_dir_str`
+ - `examples_dir_str`
+ - `repo_root_dir_str`
+ - `src_dir_str`
+
+これらを使用し始めるには、テストが `transformers.test_utils.TestCasePlus` のサブクラスに存在することを確認するだけです。例:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class PathExampleTest(TestCasePlus):
+ def test_something_involving_local_locations(self):
+ data_dir = self.tests_dir / "fixtures/tests_samples/wmt_en_ro"
+```
+
+もし、`pathlib` を介してパスを操作する必要がない場合、または単に文字列としてパスが必要な場合は、`pathlib` オブジェクトに `str()` を呼び出すか、`_str` で終わるアクセサを使用できます。例:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class PathExampleTest(TestCasePlus):
+ def test_something_involving_stringified_locations(self):
+ examples_dir = self.examples_dir_str
+```
+
+### Temporary files and directories
+
+一意の一時ファイルとディレクトリの使用は、並列テストの実行には欠かせません。これにより、テストがお互いのデータを上書きしないようにします。また、これらを作成した各テストの終了時に一時ファイルとディレクトリが削除されることを望みます。そのため、これらのニーズを満たすパッケージである `tempfile` のようなパッケージの使用は重要です。
+
+しかし、テストのデバッグ時には、一時ファイルやディレクトリに何が格納されているかを確認できる必要があり、テストを再実行するたびにランダムに変更されないその正確なパスを知りたいと思います。
+
+`transformers.test_utils.TestCasePlus` というヘルパークラスは、このような目的に最適です。これは `unittest.TestCase` のサブクラスであるため、テストモジュールで簡単に継承することができます。
+
+以下はその使用例です:
+
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class ExamplesTests(TestCasePlus):
+ def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+```
+
+このコードはユニークな一時ディレクトリを作成し、`tmp_dir` をその場所に設定します。
+
+- ユニークな一時ディレクトリを作成します:
+
+```python
+def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+```
+
+`tmp_dir` には、作成された一時ディレクトリへのパスが含まれます。期間終了後は自動的に削除されます
+テスト。
+
+- 任意の一時ディレクトリを作成し、テストの開始前にそれが空であることを確認し、テスト後には空にしないでください。
+
+```python
+def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir("./xxx")
+```
+
+これは、特定のディレクトリを監視し、前のテストがそこにデータを残さないことを確認したい場合に、デバッグに役立ちます。
+
+- `before` と `after` 引数を直接オーバーライドすることで、デフォルトの動作をオーバーライドできます。以下のいずれかの動作に導きます:
+
+ - `before=True`:テストの開始時に常に一時ディレクトリがクリアされます。
+ - `before=False`:一時ディレクトリが既に存在する場合、既存のファイルはそのままになります。
+ - `after=True`:テストの終了時に常に一時ディレクトリが削除されます。
+ - `after=False`:テストの終了時に常に一時ディレクトリはそのままになります。
+
+
+
+`rm -r`の相当を安全に実行するために、明示的な `tmp_dir` が使用される場合、プロジェクトリポジトリのチェックアウトのサブディレクトリのみが許可されます。誤って `/tmp` などのファイルシステムの重要な部分が削除されないように、常に `./` から始まるパスを渡してください。
+
+
+
+
+
+各テストは複数の一時ディレクトリを登録でき、要求がない限りすべて自動で削除されます。
+
+
+
+### Temporary sys.path override
+
+別のテストからインポートするために一時的に `sys.path` をオーバーライドする必要がある場合、`ExtendSysPath` コンテキストマネージャを使用できます。例:
+
+
+```python
+import os
+from transformers.testing_utils import ExtendSysPath
+
+bindir = os.path.abspath(os.path.dirname(__file__))
+with ExtendSysPath(f"{bindir}/.."):
+ from test_trainer import TrainerIntegrationCommon # noqa
+```
+
+### Skipping tests
+
+これは、バグが見つかり、新しいテストが作成された場合であっても、バグがまだ修正されていない場合に役立ちます。メインリポジトリにコミットできるようにするには、`make test` の実行中にそれをスキップする必要があります。
+
+メソッド:
+
+- **skip** は、テストが特定の条件が満たされた場合にのみパスすることを期待しており、それ以外の場合は pytest がテストの実行をスキップします。一般的な例は、Windows専用のテストを非Windowsプラットフォームでスキップする場合、または現在利用できない外部リソースに依存するテストをスキップする場合です(例: データベースが利用できない場合)。
+
+- **xfail** は、何らかの理由でテストが失敗することを期待しています。一般的な例は、まだ実装されていない機能のテストや、まだ修正されていないバグのテストです。テストが予想される失敗にもかかわらずパスした場合(pytest.mark.xfailでマークされたテスト)、それはxpassとしてテストサマリーに報告されます。
+
+これらの2つの間の重要な違いの1つは、`skip` はテストを実行しない点であり、`xfail` は実行します。したがって、バグのあるコードが他のテストに影響を与える場合は、`xfail` を使用しないでください。
+
+#### Implementation
+
+- テスト全体を無条件にスキップする方法は次のとおりです:
+
+
+```python no-style
+@unittest.skip(reason="this bug needs to be fixed")
+def test_feature_x():
+```
+
+または pytest 経由:
+
+```python no-style
+@pytest.mark.skip(reason="this bug needs to be fixed")
+```
+
+または `xfail` の方法:
+
+```python no-style
+@pytest.mark.xfail
+def test_feature_x():
+```
+
+
+- テスト内の内部チェックに基づいてテストをスキップする方法は次のとおりです。
+
+```python
+def test_feature_x():
+ if not has_something():
+ pytest.skip("unsupported configuration")
+```
+
+またはモジュール全体:
+
+```python
+import pytest
+
+if not pytest.config.getoption("--custom-flag"):
+ pytest.skip("--custom-flag is missing, skipping tests", allow_module_level=True)
+```
+
+または `xfail` の方法:
+
+```python
+def test_feature_x():
+ pytest.xfail("expected to fail until bug XYZ is fixed")
+```
+
+- 一部のインポートが欠落している場合にモジュール内のすべてのテストをスキップする方法は次のとおりです。
+
+```python
+docutils = pytest.importorskip("docutils", minversion="0.3")
+```
+
+- 条件に基づいてテストをスキップします。
+
+```python no-style
+@pytest.mark.skipif(sys.version_info < (3,6), reason="requires python3.6 or higher")
+def test_feature_x():
+```
+
+または:
+
+```python no-style
+@unittest.skipIf(torch_device == "cpu", "Can't do half precision")
+def test_feature_x():
+```
+
+
+またはモジュール全体をスキップします。
+
+```python no-style
+@pytest.mark.skipif(sys.platform == 'win32', reason="does not run on windows")
+class TestClass():
+ def test_feature_x(self):
+```
+
+詳細、例、および方法についての詳細は[こちら](https://docs.pytest.org/en/latest/skipping.html)を参照してください。
+
+### Slow tests
+
+テストライブラリは着実に成長しており、テストの一部は数分かかります。そのため、CIでテストスイートの完了を待つのは1時間待つ余裕がないことがあります。したがって、いくつかの例外を除いて、遅いテストは以下の例のようにマークすべきです:
+
+
+```python no-style
+from transformers.testing_utils import slow
+@slow
+def test_integration_foo():
+```
+
+
+テストが`@slow`としてマークされたら、そのようなテストを実行するには、環境変数 `RUN_SLOW=1`を設定します。例:
+
+```bash
+RUN_SLOW=1 pytest tests
+```
+
+`@parameterized` のようなデコレータはテスト名を書き換えるため、`@slow` および他のスキップデコレータ `@require_*` は正しく動作するためには、最後にリストアップする必要があります。以下は正しい使用例の一例です:
+
+
+```python no-style
+@parameterized.expand(...)
+@slow
+def test_integration_foo():
+```
+
+このドキュメントの冒頭で説明したように、遅いテストは定期的なスケジュールに従って実行され、PRのCIチェックでは実行されません。そのため、一部の問題がPRの提出時に見落とされ、マージされる可能性があります。そのような問題は次回のスケジュールされたCIジョブで検出されます。しかし、それはまた、PRを提出する前に自分のマシンで遅いテストを実行する重要性を意味しています。
+
+どのテストを遅いテストとしてマークすべきかを選択するための、おおまかな意思決定メカニズムが次に示されています:
+
+- テストがライブラリの内部コンポーネントの1つに焦点を当てている場合(例: モデリングファイル、トークン化ファイル、パイプライン)、そのテストは遅いテストスイートで実行する必要があります。それがライブラリの他の側面、たとえばドキュメンテーションや例に焦点を当てている場合、それらのテストは遅いテストスイートで実行する必要があります。そして、このアプローチを洗練させるために例外を設ける必要があります。
+
+- 重いウェイトセットや約50MB以上のデータセットをダウンロードする必要があるすべてのテスト(例: モデル統合テスト、トークナイザ統合テスト、パイプライン統合テスト)は遅いテストとして設定する必要があります。新しいモデルを追加する場合、統合テスト用にランダムなウェイトを持つ小さなバージョンを作成し、ハブにアップロードする必要があります。これについては以下の段落で詳しく説明します。
+
+- 特に高速化されていないトレーニングを行う必要があるすべてのテストは遅いテストとして設定する必要があります。
+
+- 一部の「遅い」であるべきでないテストが非常に遅い場合、およびそれらを `@slow` として設定する必要がある場合には例外を導入できます。大容量のファイルをディスクに保存および読み込みする自動モデリングテストは、`@slow` としてマークされたテストの良い例です。
+
+- CIで1秒未満でテストが完了する場合(ダウンロードを含む)、それは通常のテストであるべきです。
+
+すべての非遅いテストは、さまざまな内部要素を完全にカバーする必要がありますが、高速である必要があります。たとえば、特別に作成された小さなモデル(レイヤー数が最小限で、語彙サイズが小さいなど)を使用して、かなりのカバレッジを実現できます。その後、`@slow` テストでは大規模な遅いモデルを使用して質的なテストを実行できます。これらを使用するには、以下のように *tiny* モデルを探してください:
+
+
+```bash
+grep tiny tests examples
+```
+
+[スクリプトの例](https://github.com/huggingface/transformers/tree/main/scripts/fsmt/fsmt-make-tiny-model.py)があり、これにより tiny-wmt19-en-de のような小さなモデルが作成されます。特定のモデルのアーキテクチャに簡単に調整できます。
+
+実行時間を誤って測定することが簡単です。たとえば、巨大なモデルのダウンロードに関するオーバーヘッドがある場合、ローカルでテストするとダウンロードされたファイルがキャッシュされ、ダウンロード時間が計測されなくなります。したがって、CIログの実行速度レポート(`pytest --durations=0 tests` の出力)を確認してください。
+
+このレポートは、遅いテストとしてマークされていない遅い外れ値や、高速に書き直す必要があるテストを見つけるのにも役立ちます。テストスイートがCIで遅くなり始めた場合、このレポートのトップリストには最も遅いテストが表示されます。
+
+### Testing the stdout/stderr output
+
+`stdout` および/または `stderr` に書き込む関数をテストするために、テストは `pytest` の [capsys システム](https://docs.pytest.org/en/latest/capture.html) を使用してこれらのストリームにアクセスできます。以下はその方法です:
+
+
+```python
+import sys
+
+
+def print_to_stdout(s):
+ print(s)
+
+
+def print_to_stderr(s):
+ sys.stderr.write(s)
+
+
+def test_result_and_stdout(capsys):
+ msg = "Hello"
+ print_to_stdout(msg)
+ print_to_stderr(msg)
+ out, err = capsys.readouterr() # consume the captured output streams
+ # optional: if you want to replay the consumed streams:
+ sys.stdout.write(out)
+ sys.stderr.write(err)
+ # test:
+ assert msg in out
+ assert msg in err
+```
+
+
+そしてもちろん、ほとんどの場合、`stderr`は例外の一部として提供されるため、そのような場合には try/excel を使用する必要があります。
+ケース:
+
+```python
+def raise_exception(msg):
+ raise ValueError(msg)
+
+
+def test_something_exception():
+ msg = "Not a good value"
+ error = ""
+ try:
+ raise_exception(msg)
+ except Exception as e:
+ error = str(e)
+ assert msg in error, f"{msg} is in the exception:\n{error}"
+```
+
+
+stdout をキャプチャするもう 1 つのアプローチは、`contextlib.redirect_stdout`を使用することです。
+
+```python
+from io import StringIO
+from contextlib import redirect_stdout
+
+
+def print_to_stdout(s):
+ print(s)
+
+
+def test_result_and_stdout():
+ msg = "Hello"
+ buffer = StringIO()
+ with redirect_stdout(buffer):
+ print_to_stdout(msg)
+ out = buffer.getvalue()
+ # optional: if you want to replay the consumed streams:
+ sys.stdout.write(out)
+ # test:
+ assert msg in out
+```
+
+stdout をキャプチャする際の重要な潜在的な問題は、通常の `print` でこれまでに出力された内容をリセットする可能性がある `\r` 文字が含まれている可能性があることです。`pytest` 自体には問題はありませんが、`pytest -s` ではこれらの文字がバッファに含まれるため、`-s` ありとなしでテストを実行できるようにするには、`re.sub(r'~.*\r', '', buf, 0, re.M)` を使用してキャプチャされた出力に対して追加のクリーンアップを行う必要があります。
+
+しかし、その後、`\r` が含まれているかどうかにかかわらず、すべての操作を自動的に処理するヘルパーコンテキストマネージャラッパーがあります。したがって、次のように簡単に行えます:
+
+
+```python
+from transformers.testing_utils import CaptureStdout
+
+with CaptureStdout() as cs:
+ function_that_writes_to_stdout()
+print(cs.out)
+```
+
+完全なテスト例は次のとおりです。
+
+```python
+from transformers.testing_utils import CaptureStdout
+
+msg = "Secret message\r"
+final = "Hello World"
+with CaptureStdout() as cs:
+ print(msg + final)
+assert cs.out == final + "\n", f"captured: {cs.out}, expecting {final}"
+```
+
+`stderr` をキャプチャしたい場合は、代わりに `CaptureStderr` クラスを使用してください。
+
+```python
+from transformers.testing_utils import CaptureStderr
+
+with CaptureStderr() as cs:
+ function_that_writes_to_stderr()
+print(cs.err)
+```
+
+両方のストリームを一度にキャプチャする必要がある場合は、親の `CaptureStd` クラスを使用します。
+
+```python
+from transformers.testing_utils import CaptureStd
+
+with CaptureStd() as cs:
+ function_that_writes_to_stdout_and_stderr()
+print(cs.err, cs.out)
+```
+
+
+また、テストの問題のデバッグを支援するために、デフォルトで、これらのコンテキスト マネージャーは終了時にキャプチャされたストリームを自動的に再生します。
+文脈から。
+
+### Capturing logger stream
+
+ロガーの出力を検証する必要がある場合は、`CaptureLogger`を使用できます。
+
+```python
+from transformers import logging
+from transformers.testing_utils import CaptureLogger
+
+msg = "Testing 1, 2, 3"
+logging.set_verbosity_info()
+logger = logging.get_logger("transformers.models.bart.tokenization_bart")
+with CaptureLogger(logger) as cl:
+ logger.info(msg)
+assert cl.out, msg + "\n"
+```
+
+### Testing with environment variables
+
+特定のテストで環境変数の影響をテストしたい場合は、ヘルパー デコレータを使用できます。
+`transformers.testing_utils.mockenv`
+
+```python
+from transformers.testing_utils import mockenv
+
+
+class HfArgumentParserTest(unittest.TestCase):
+ @mockenv(TRANSFORMERS_VERBOSITY="error")
+ def test_env_override(self):
+ env_level_str = os.getenv("TRANSFORMERS_VERBOSITY", None)
+```
+
+場合によっては、外部プログラムを呼び出す必要があるため、`os.environ` に`PYTHONPATH`を設定してインクルードする必要があります。
+複数のローカル パス。ヘルパー クラス `transformers.test_utils.TestCasePlus` が役に立ちます。
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class EnvExampleTest(TestCasePlus):
+ def test_external_prog(self):
+ env = self.get_env()
+ # now call the external program, passing `env` to it
+```
+
+テストファイルが `tests` テストスイートまたは `examples` のどちらにあるかに応じて
+`env[PYTHONPATH]` を使用して、これら 2 つのディレクトリのいずれかを含めます。また、テストが確実に行われるようにするための `src` ディレクトリも含めます。
+現在のリポジトリに対して実行され、最後に、テストが実行される前にすでに設定されていた `env[PYTHONPATH]` を使用して実行されます。
+何かあれば呼ばれます。
+
+このヘルパー メソッドは `os.environ` オブジェクトのコピーを作成するため、元のオブジェクトはそのまま残ります。
+
+
+### Getting reproducible results
+
+状況によっては、テストのランダム性を削除したい場合があります。同一の再現可能な結果セットを取得するには、
+シードを修正する必要があります:
+
+```python
+seed = 42
+
+# python RNG
+import random
+
+random.seed(seed)
+
+# pytorch RNGs
+import torch
+
+torch.manual_seed(seed)
+torch.backends.cudnn.deterministic = True
+if torch.cuda.is_available():
+ torch.cuda.manual_seed_all(seed)
+
+# numpy RNG
+import numpy as np
+
+np.random.seed(seed)
+
+# tf RNG
+tf.random.set_seed(seed)
+```
+
+
+### Debugging tests
+
+警告が発生した時点でデバッガーを開始するには、次の手順を実行します。
+
+```bash
+pytest tests/utils/test_logging.py -W error::UserWarning --pdb
+```
+
+## Working with github actions workflows
+
+セルフプッシュのワークフローCIジョブをトリガーするには、以下の手順を実行する必要があります:
+
+1. `transformers` のリモートリポジトリで新しいブランチを作成します(フォークではなく、元のリポジトリで行います)。
+2. ブランチの名前は `ci_` または `ci-` で始まる必要があります(`main` もトリガーしますが、`main` ではPRを作成できません)。また、特定のパスでのみトリガーされます - このドキュメントが書かれた後に変更された場合に備えて、最新の定義は[こちら](https://github.com/huggingface/transformers/blob/main/.github/workflows/self-push.yml)の *push:* にあります。
+3. このブランチからPRを作成します。
+4. その後、このジョブが[ここ](https://github.com/huggingface/transformers/actions/workflows/self-push.yml)に表示されます。ジョブはバックログがある場合、すぐに実行されないことがあります。
+
+## Testing Experimental CI Features
+
+CI機能のテストは通常のCIの正常な動作に干渉する可能性があるため、新しいCI機能を追加する場合、以下の手順に従う必要があります。
+
+1. テストが必要なものをテストするための新しい専用のジョブを作成します。
+2. 新しいジョブは常に成功する必要があるため、常にグリーン ✓(詳細は以下参照)を表示する必要があります。
+3. さまざまな種類のPR(ユーザーフォークブランチ、非フォークブランチ、github.com UIから直接ファイルを編集するブランチ、さまざまな強制プッシュなど)が実行されるまでいくつかの日間実行し、実験的なジョブのログを監視します(意図的に常にグリーンになるようになっている全体のジョブの緑ではなく)。
+4. すべてが安定していることが明確になったら、新しい変更を既存のジョブに統合します。
+
+このように、CI機能自体の実験が通常のワークフローに干渉しないようにできます。
+
+では、新しいCI機能が開発中である間、ジョブを常に成功させるにはどうすればいいでしょうか?
+
+TravisCIのような一部のCIは `ignore-step-failure` をサポートし、全体のジョブを成功として報告しますが、この文書が作成された時点ではCircleCIとGithub Actionsはそれをサポートしていません。
+
+したがって、以下のワークアラウンドを使用できます:
+
+1. bashスクリプト内で潜在的な失敗を抑制するために実行コマンドの冒頭に `set +euo pipefail` を記述します。
+2. 最後のコマンドは成功する必要があります。たとえば `echo "done"` または単に `true` を使用できます。
+
+以下は例です:
+
+
+
+```yaml
+- run:
+ name: run CI experiment
+ command: |
+ set +euo pipefail
+ echo "setting run-all-despite-any-errors-mode"
+ this_command_will_fail
+ echo "but bash continues to run"
+ # emulate another failure
+ false
+ # but the last command must be a success
+ echo "during experiment do not remove: reporting success to CI, even if there were failures"
+```
+
+
+単純なコマンドの場合は、次のようにすることもできます。
+
+```bash
+cmd_that_may_fail || true
+```
+
+もちろん、結果に満足したら、実験的なステップやジョブを通常のジョブと統合し、`set +euo pipefail` などの追加した要素を削除して、実験的なジョブが通常のCIの動作に干渉しないようにします。
+
+このプロセス全体は、実験的なステップに対して `allow-failure` のようなものを設定し、PRの全体のステータスに影響を与えずに失敗させることができれば、はるかに簡単になったでしょう。しかし、前述の通り、現在はCircleCIとGithub Actionsはこの機能をサポートしていません。
+
+この機能に関しての投票や、CIに特有のスレッドでその進捗状況を確認できます:
+
+- [Github Actions:](https://github.com/actions/toolkit/issues/399)
+- [CircleCI:](https://ideas.circleci.com/ideas/CCI-I-344)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tf_xla.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tf_xla.md
new file mode 100644
index 0000000000000000000000000000000000000000..1f5a2af1a5a2880268423324f65e8c5780337397
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tf_xla.md
@@ -0,0 +1,179 @@
+
+
+# XLA Integration for TensorFlow Models
+
+[[open-in-colab]]
+
+加速線形代数(Accelerated Linear Algebra)、通称XLAは、TensorFlowモデルのランタイムを高速化するためのコンパイラです。[公式ドキュメント](https://www.tensorflow.org/xla)によれば、XLA(Accelerated Linear Algebra)は線形代数のためのドメイン固有のコンパイラで、TensorFlowモデルを潜在的にソースコードの変更なしで高速化できます。
+
+TensorFlowでXLAを使用するのは簡単です。XLAは`tensorflow`ライブラリ内にパッケージ化されており、[`tf.function`](https://www.tensorflow.org/guide/intro_to_graphs)などのグラフを作成する関数内で`jit_compile`引数を使用してトリガーできます。`fit()`や`predict()`などのKerasメソッドを使用する場合、`model.compile()`に`jit_compile`引数を渡すだけでXLAを有効にできます。ただし、XLAはこれらのメソッドに限定されているわけではありません。任意の`tf.function`を高速化するためにも使用できます。
+
+🤗 Transformers内のいくつかのTensorFlowメソッドは、XLAと互換性があるように書き直されています。これには、[GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2)、[T5](https://huggingface.co/docs/transformers/model_doc/t5)、[OPT](https://huggingface.co/docs/transformers/model_doc/opt)などのテキスト生成モデルや、[Whisper](https://huggingface.co/docs/transformers/model_doc/whisper)などの音声処理モデルも含まれます。
+
+速度向上の具体的な量はモデルに非常に依存しますが、🤗 Transformers内のTensorFlowテキスト生成モデルでは、約100倍の速度向上を確認しています。このドキュメントでは、これらのモデルにXLAを使用して最大のパフォーマンスを得る方法を説明します。また、ベンチマークとXLA統合のデザイン哲学について詳しく学びたい場合の追加リソースへのリンクも提供します。
+
+## Running TF functions with XLA
+
+以下のTensorFlowモデルを考えてみましょう:
+
+
+```py
+import tensorflow as tf
+
+model = tf.keras.Sequential(
+ [tf.keras.layers.Dense(10, input_shape=(10,), activation="relu"), tf.keras.layers.Dense(5, activation="softmax")]
+)
+```
+
+上記のモデルは、次元が`(10, )`の入力を受け入れます。このモデルをフォワードパスで実行するには、次のようにします:
+
+
+```py
+# Generate random inputs for the model.
+batch_size = 16
+input_vector_dim = 10
+random_inputs = tf.random.normal((batch_size, input_vector_dim))
+
+# Run a forward pass.
+_ = model(random_inputs)
+```
+
+XLAでコンパイルされた関数を使用してフォワードパスを実行するには、以下のようにします:
+
+
+```py
+xla_fn = tf.function(model, jit_compile=True)
+_ = xla_fn(random_inputs)
+```
+
+`model`のデフォルトの `call()` 関数はXLAグラフをコンパイルするために使用されます。ただし、XLAにコンパイルしたい他のモデル関数がある場合、それも可能です。以下はその方法です:
+
+
+```py
+my_xla_fn = tf.function(model.my_xla_fn, jit_compile=True)
+```
+
+## Running a TF text generation model with XLA from 🤗 Transformers
+
+🤗 Transformers内でXLAでの高速化された生成を有効にするには、最新バージョンの`transformers`がインストールされている必要があります。次のコマンドを実行してインストールできます:
+
+```bash
+pip install transformers --upgrade
+```
+
+次に、次のコードを実行できます:
+
+
+```py
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+# Will error if the minimal version of Transformers is not installed.
+from transformers.utils import check_min_version
+
+check_min_version("4.21.0")
+
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token=" ")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+input_string = ["TensorFlow is"]
+
+# One line to create an XLA generation function
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+tokenized_input = tokenizer(input_string, return_tensors="tf")
+generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+
+decoded_text = tokenizer.decode(generated_tokens[0], skip_special_tokens=True)
+print(f"Generated -- {decoded_text}")
+# Generated -- TensorFlow is an open-source, open-source, distributed-source application # framework for the
+```
+
+`generate()`でXLAを有効にするのは、たった一行のコードです。コードの残り部分は変更されていません。ただし、XLA固有のいくつかの注意点が上記のコードスニペットにあります。これらに注意する必要があり、XLAがもたらす速度向上を実現するためにそれらを把握することが重要です。次のセクションでこれらについて詳しく説明します。
+
+
+## Gotchas to be aware of
+
+XLAを有効にした関数(上記の`xla_generate()`など)を初めて実行すると、内部で計算グラフを推論しようとしますが、これは時間がかかります。このプロセスは["トレーシング"(tracing)](https://www.tensorflow.org/guide/intro_to_graphs#when_is_a_function_tracing)として知られています。
+
+生成時間が高速ではないことに気付くかもしれません。`xla_generate()`(または他のXLA対応関数)の連続呼び出しでは、関数への入力が最初に計算グラフが構築されたときと同じ形状に従っている場合、計算グラフを推論する必要はありません。これは、入力形状が固定されているモダリティ(例:画像)には問題ありませんが、変数の入力形状モダリティ(例:テキスト)を扱う場合には注意が必要です。
+
+`xla_generate()`が常に同じ入力形状で動作するようにするには、トークナイザを呼び出す際に`padding`引数を指定できます。
+
+```py
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+input_string = ["TensorFlow is"]
+
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+# Here, we call the tokenizer with padding options.
+tokenized_input = tokenizer(input_string, pad_to_multiple_of=8, padding=True, return_tensors="tf")
+
+generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+decoded_text = tokenizer.decode(generated_tokens[0], skip_special_tokens=True)
+print(f"Generated -- {decoded_text}")
+```
+
+これにより、`xla_generate()`への入力が常にトレースされた形状の入力を受け取ることを確認し、生成時間の高速化を実現できます。以下のコードでこれを確認できます:
+
+```py
+import time
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+for input_string in ["TensorFlow is", "TensorFlow is a", "TFLite is a"]:
+ tokenized_input = tokenizer(input_string, pad_to_multiple_of=8, padding=True, return_tensors="tf")
+ start = time.time_ns()
+ generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+ end = time.time_ns()
+ print(f"Execution time -- {(end - start) / 1e6:.1f} ms\n")
+```
+
+Tesla T4 GPUを使用すると、次のような出力が期待されます:
+
+```bash
+Execution time -- 30819.6 ms
+
+Execution time -- 79.0 ms
+
+Execution time -- 78.9 ms
+```
+
+最初の`xla_generate()`呼び出しはトレーシングのために時間がかかりますが、連続する呼び出しは桁違いに高速です。生成オプションのいかなる変更も、再トレーシングを引き起こし、生成時間の遅延を引き起こすことに注意してください。
+
+このドキュメントでは、🤗 Transformersが提供するテキスト生成オプションをすべて網羅していません。高度なユースケースについてはドキュメンテーションを参照することをお勧めします。
+
+## Additional Resources
+
+ここでは、🤗 Transformersと一般的なXLAについてさらに詳しく学びたい場合のいくつかの追加リソースを提供します。
+
+* [このColab Notebook](https://colab.research.google.com/github/huggingface/blog/blob/main/notebooks/91_tf_xla_generate.ipynb)では、XLA対応のエンコーダーデコーダー([T5](https://huggingface.co/docs/transformers/model_doc/t5)など)およびデコーダー専用([GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2)など)テキスト生成モデルを試すための対話型デモが提供されています。
+* [このブログ記事](https://huggingface.co/blog/tf-xla-generate)では、XLA対応モデルの比較ベンチマークの概要と、TensorFlowでのXLAについての友好的な紹介が提供されています。
+* [このブログ記事](https://blog.tensorflow.org/2022/11/how-hugging-face-improved-text-generation-performance-with-xla.html)では、🤗 TransformersのTensorFlowモデルにXLAサポートを追加する際の設計哲学について説明しています。
+* 一般的なXLAとTensorFlowグラフについて詳しく学ぶためのおすすめの投稿:
+ * [XLA: 機械学習用の最適化コンパイラ](https://www.tensorflow.org/xla)
+ * [グラフと`tf.function`の紹介](https://www.tensorflow.org/guide/intro_to_graphs)
+ * [`tf.function`を使用したパフォーマンス向上](https://www.tensorflow.org/guide/function)
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tflite.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tflite.md
new file mode 100644
index 0000000000000000000000000000000000000000..ad3e9a3f484e2ce157a23cf0b58d1854efc8a267
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tflite.md
@@ -0,0 +1,58 @@
+
+
+# Export to TFLite
+
+[TensorFlow Lite](https://www.tensorflow.org/lite/guide)は、モバイルフォン、組み込みシステム、およびモノのインターネット(IoT)デバイスなど、リソースに制約のあるデバイスに機械学習モデルを展開するための軽量なフレームワークです。TFLiteは、計算能力、メモリ、および電力消費が限られているこれらのデバイス上でモデルを効率的に最適化して実行するために設計されています。
+TensorFlow Liteモデルは、`.tflite`ファイル拡張子で識別される特別な効率的なポータブル形式で表されます。
+
+🤗 Optimumは、🤗 TransformersモデルをTFLiteにエクスポートするための機能を`exporters.tflite`モジュールを介して提供しています。サポートされているモデルアーキテクチャのリストについては、[🤗 Optimumのドキュメント](https://huggingface.co/docs/optimum/exporters/tflite/overview)をご参照ください。
+
+モデルをTFLiteにエクスポートするには、必要な依存関係をインストールしてください:
+
+
+```bash
+pip install optimum[exporters-tf]
+```
+
+すべての利用可能な引数を確認するには、[🤗 Optimumドキュメント](https://huggingface.co/docs/optimum/main/en/exporters/tflite/usage_guides/export_a_model)を参照するか、コマンドラインでヘルプを表示してください:
+
+```bash
+optimum-cli export tflite --help
+```
+
+🤗 Hubからモデルのチェックポイントをエクスポートするには、例えば `google-bert/bert-base-uncased` を使用する場合、次のコマンドを実行します:
+
+```bash
+optimum-cli export tflite --model google-bert/bert-base-uncased --sequence_length 128 bert_tflite/
+```
+
+進行状況を示すログが表示され、生成された `model.tflite` が保存された場所も表示されるはずです:
+
+```bash
+Validating TFLite model...
+ -[✓] TFLite model output names match reference model (logits)
+ - Validating TFLite Model output "logits":
+ -[✓] (1, 128, 30522) matches (1, 128, 30522)
+ -[x] values not close enough, max diff: 5.817413330078125e-05 (atol: 1e-05)
+The TensorFlow Lite export succeeded with the warning: The maximum absolute difference between the output of the reference model and the TFLite exported model is not within the set tolerance 1e-05:
+- logits: max diff = 5.817413330078125e-05.
+ The exported model was saved at: bert_tflite
+ ```
+
+上記の例は🤗 Hubからチェックポイントをエクスポートする方法を示しています。ローカルモデルをエクスポートする場合、まずモデルの重みファイルとトークナイザファイルを同じディレクトリ(`local_path`)に保存したことを確認してください。CLIを使用する場合、🤗 Hubのチェックポイント名の代わりに`model`引数に`local_path`を渡します。
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tokenizer_summary.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tokenizer_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..448ad9c871aaa340de9d2b6f954549c8849091d3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/tokenizer_summary.md
@@ -0,0 +1,179 @@
+
+
+# Summary of the tokenizers
+
+[[open-in-colab]]
+
+このページでは、トークナイゼーションについて詳しく見ていきます。
+
+", "ug"] としてトークン化されます。 一般的に、"m" のような単一の文字は、トレーニングデータには通常、各文字の少なくとも1つの出現が含まれているため、"" シンボルに置き換えられることはありませんが、絵文字のような非常に特殊な文字の場合には発生する可能性があります。
+
+前述のように、ボキャブラリサイズ、すなわちベースボキャブラリサイズ + マージの回数は選択するハイパーパラメータです。 例えば、[GPT](model_doc/gpt) はベース文字が478文字で、40,000回のマージ後にトレーニングを停止したため、ボキャブラリサイズは40,478です。
+
+#### Byte-level BPE
+
+すべてのUnicode文字をベース文字と考えると、すべての可能なベース文字が含まれるかもしれないベースボキャブラリはかなり大きくなることがあります。 [GPT-2](https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf) は、ベースボキャブラリを256バイトにする賢いトリックとしてバイトをベースボキャブラリとして使用し、すべてのベース文字がボキャブラリに含まれるようにしています。 パンクチュエーションを扱うためのいくつかの追加ルールを備えたGPT2のトークナイザは、 シンボルを必要とせずにすべてのテキストをトークン化できます。 [GPT-2](model_doc/gpt) は50,257のボキャブラリサイズを持っており、これは256バイトのベーストークン、特別なテキストの終了を示すトークン、および50,000回のマージで学習したシンボルに対応しています。
+
+### WordPiece
+
+WordPieceは、[BERT](model_doc/bert)、[DistilBERT](model_doc/distilbert)、および[Electra](model_doc/electra)で使用されるサブワードトークナイゼーションアルゴリズムです。 このアルゴリズムは、[Japanese and Korean Voice Search (Schuster et al., 2012)](https://static.googleusercontent.com/media/research.google.com/ja//pubs/archive/37842.pdf) で概説されており、BPEに非常に似ています。 WordPieceは最も頻繁なシンボルペアを選択するのではなく、トレーニングデータに追加した場合にトレーニングデータの尤度を最大化するシンボルペアを選択します。
+
+これは具体的にはどういう意味ですか?前の例を参照すると、トレーニングデータの尤度を最大化することは、そのシンボルペアの確率をその最初のシンボルに続く2番目のシンボルの確率で割ったものが、すべてのシンボルペアの中で最も大きい場合に該当するシンボルペアを見つけることに等しいです。 たとえば、"u" の後に "g" が続く場合、他のどのシンボルペアよりも "ug" の確率を "u"、"g" で割った確率が高ければ、それらのシンボルは結合されます。直感的に言えば、WordPieceは2つのシンボルを結合することによって失われるものを評価し、それがそれに値するかどうかを確認する点でBPEとはわずかに異なります。
+
+### Unigram
+
+Unigramは、[Subword Regularization: Improving Neural Network Translation Models with Multiple Subword Candidates (Kudo, 2018)](https://arxiv.org/pdf/1804.10959.pdf) で導入されたサブワードトークナイゼーションアルゴリズムです。 BPEやWordPieceとは異なり、Unigramはベースボキャブラリを多数のシンボルで初期化し、各シンボルを削減してより小さなボキャブラリを取得します。 ベースボキャブラリは、事前にトークン化されたすべての単語と最も一般的な部分文字列に対応する可能性があります。 Unigramはtransformersのモデルの直接の使用には適していませんが、[SentencePiece](#sentencepiece)と組み合わせて使用されます。
+
+各トレーニングステップで、Unigramアルゴリズムは現在のボキャブラリとユニグラム言語モデルを使用してトレーニングデータ上の損失(通常は対数尤度として定義)を定義します。その後、ボキャブラリ内の各シンボルについて、そのシンボルがボキャブラリから削除された場合に全体の損失がどれだけ増加するかを計算します。 Unigramは、損失の増加が最も低いp(通常は10%または20%)パーセントのシンボルを削除します。つまり、トレーニングデータ全体の損失に最も影響を与えない、最も損失の少ないシンボルを削除します。 このプロセスは、ボキャブラリが望ましいサイズに達するまで繰り返されます。 Unigramアルゴリズムは常にベース文字を保持するため、任意の単語をトークン化できます。
+
+Unigramはマージルールに基づいていないため(BPEとWordPieceとは対照的に)、トレーニング後の新しいテキストのトークン化にはいくつかの方法があります。例として、トレーニングされたUnigramトークナイザが持つボキャブラリが次のような場合:
+
+
+```
+["b", "g", "h", "n", "p", "s", "u", "ug", "un", "hug"],
+```
+
+`"hugs"`は、`["hug", "s"]`、`["h", "ug", "s"]`、または`["h", "u", "g", "s"]`のようにトークン化できます。では、どれを選択すべきでしょうか? Unigramは、トレーニングコーパス内の各トークンの確率を保存し、トレーニング後に各可能なトークン化の確率を計算できるようにします。このアルゴリズムは実際には最も可能性の高いトークン化を選択しますが、確率に従って可能なトークン化をサンプリングするオプションも提供します。
+
+これらの確率は、トークナイザーがトレーニングに使用する損失によって定義されます。トレーニングデータが単語 \\(x_{1}, \dots, x_{N}\\) で構成され、単語 \\(x_{i}\\) のすべての可能なトークン化のセットが \\(S(x_{i})\\) と定義される場合、全体の損失は次のように定義されます。
+
+$$\mathcal{L} = -\sum_{i=1}^{N} \log \left ( \sum_{x \in S(x_{i})} p(x) \right )$$
+
+
+
+これはTorchScriptを使用した実験の最初であり、可変入力サイズのモデルに対するその能力をまだ探求中です。これは私たちの関心の焦点であり、今後のリリースでは、より柔軟な実装や、PythonベースのコードとコンパイルされたTorchScriptを比較するベンチマークを含む、より多くのコード例で詳細な分析を行います。
+
+
+
+[TorchScriptのドキュメント](https://pytorch.org/docs/stable/jit.html)によれば:
+
+> TorchScriptは、PyTorchコードから直列化および最適化可能なモデルを作成する方法です。
+
+TorchScriptを使用すると、効率志向のC++プログラムなど、他のプログラムでモデルを再利用できるようになります。PyTorchベースのPythonプログラム以外の環境で🤗 Transformersモデルをエクスポートして使用するためのインターフェースを提供しています。ここでは、TorchScriptを使用してモデルをエクスポートし、使用する方法を説明します。
+
+モデルをエクスポートするには、次の2つの要件があります:
+
+- `torchscript`フラグを使用したモデルのインスタンス化
+- ダミーの入力を使用したフォワードパス
+
+これらの必要条件は、以下で詳細に説明されているように、開発者が注意する必要があるいくつかのことを意味します。
+
+## TorchScript flag and tied weights
+
+`torchscript`フラグは、ほとんどの🤗 Transformers言語モデルにおいて、`Embedding`レイヤーと`Decoding`レイヤー間で重みが連結されているため必要です。
+TorchScriptでは、重みが連結されているモデルをエクスポートすることはできませんので、事前に重みを切り離して複製する必要があります。
+
+`torchscript`フラグを使用してインスタンス化されたモデルは、`Embedding`レイヤーと`Decoding`レイヤーが分離されており、そのため後でトレーニングしてはいけません。
+トレーニングは、これらの2つのレイヤーを非同期にする可能性があり、予期しない結果をもたらす可能性があります。
+
+言語モデルヘッドを持たないモデルには言及しませんが、これらのモデルには連結された重みが存在しないため、`torchscript`フラグなしで安全にエクスポートできます。
+
+## Dummy inputs and standard lengths
+
+ダミー入力はモデルのフォワードパスに使用されます。入力の値はレイヤーを通じて伝播される間、PyTorchは各テンソルに実行された異なる操作を追跡します。これらの記録された操作は、モデルの*トレース*を作成するために使用されます。
+
+トレースは入力の寸法に対して作成されます。そのため、ダミー入力の寸法に制約され、他のシーケンス長やバッチサイズでは動作しません。異なるサイズで試すと、以下のエラーが発生します:
+
+```
+`The expanded size of the tensor (3) must match the existing size (7) at non-singleton dimension 2`
+```
+
+お勧めしますのは、モデルの推論中に供給される最大の入力と同じ大きさのダミー入力サイズでモデルをトレースすることです。パディングを使用して不足値を補完することもできます。ただし、モデルがより大きな入力サイズでトレースされるため、行列の寸法も大きくなり、より多くの計算が発生します。
+
+異なるシーケンス長のモデルをエクスポートする際に、各入力に対して実行される演算の総数に注意して、パフォーマンスを密接にフォローすることをお勧めします。
+
+## Using TorchScript in Python
+
+このセクションでは、モデルの保存と読み込み、および推論にトレースを使用する方法を示します。
+
+### Saving a model
+
+TorchScriptで`BertModel`をエクスポートするには、`BertConfig`クラスから`BertModel`をインスタンス化し、それをファイル名`traced_bert.pt`でディスクに保存します:
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+
+enc = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+
+# Tokenizing input text
+text = "[CLS] Who was Jim Henson ? [SEP] Jim Henson was a puppeteer [SEP]"
+tokenized_text = enc.tokenize(text)
+
+# Masking one of the input tokens
+masked_index = 8
+tokenized_text[masked_index] = "[MASK]"
+indexed_tokens = enc.convert_tokens_to_ids(tokenized_text)
+segments_ids = [0, 0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1]
+
+# Creating a dummy input
+tokens_tensor = torch.tensor([indexed_tokens])
+segments_tensors = torch.tensor([segments_ids])
+dummy_input = [tokens_tensor, segments_tensors]
+
+# Initializing the model with the torchscript flag
+# Flag set to True even though it is not necessary as this model does not have an LM Head.
+config = BertConfig(
+ vocab_size_or_config_json_file=32000,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ torchscript=True,
+)
+
+# Instantiating the model
+model = BertModel(config)
+
+# The model needs to be in evaluation mode
+model.eval()
+
+# If you are instantiating the model with *from_pretrained* you can also easily set the TorchScript flag
+model = BertModel.from_pretrained("google-bert/bert-base-uncased", torchscript=True)
+
+# Creating the trace
+traced_model = torch.jit.trace(model, [tokens_tensor, segments_tensors])
+torch.jit.save(traced_model, "traced_bert.pt")
+```
+
+### Loading a model
+
+以前に保存した `BertModel`、`traced_bert.pt` をディスクから読み込んで、以前に初期化した `dummy_input` で使用できます。
+
+```python
+loaded_model = torch.jit.load("traced_bert.pt")
+loaded_model.eval()
+
+all_encoder_layers, pooled_output = loaded_model(*dummy_input)
+```
+
+
+### Using a traced model for inference
+
+トレースモデルを使用して推論を行うには、その `__call__` ダンダーメソッドを使用します。
+
+```python
+traced_model(tokens_tensor, segments_tensors)
+```
+
+
+## Deploy Hugging Face TorchScript models to AWS with the Neuron SDK
+
+AWSはクラウドでの低コストで高性能な機械学習推論向けに [Amazon EC2 Inf1](https://aws.amazon.com/ec2/instance-types/inf1/) インスタンスファミリーを導入しました。Inf1インスタンスはAWS Inferentiaチップによって駆動され、ディープラーニング推論ワークロードに特化したカスタムビルドのハードウェアアクセラレータです。[AWS Neuron](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/#) はInferentia用のSDKで、トランスフォーマーモデルをトレースして最適化し、Inf1に展開するためのサポートを提供します。
+
+Neuron SDK が提供するもの:
+
+1. クラウドでの推論のためにTorchScriptモデルをトレースして最適化するための、1行のコード変更で使用できる簡単なAPI。
+2. [改善されたコストパフォーマンス](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/benchmark/) のためのボックス外のパフォーマンス最適化。
+3. [PyTorch](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/bert_tutorial/tutorial_pretrained_bert.html) または [TensorFlow](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/tensorflow/huggingface_bert/huggingface_bert.html) で構築されたHugging Faceトランスフォーマーモデルへのサポート。
+
+### Implications
+
+BERT(Bidirectional Encoder Representations from Transformers)アーキテクチャやその変種([distilBERT](https://huggingface.co/docs/transformers/main/model_doc/distilbert) や [roBERTa](https://huggingface.co/docs/transformers/main/model_doc/roberta) など)に基づくトランスフォーマーモデルは、非生成タスク(抽出型質問応答、シーケンス分類、トークン分類など)において、Inf1上で最適に動作します。ただし、テキスト生成タスクも [AWS Neuron MarianMT チュートリアル](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/transformers-marianmt.html) に従ってInf1上で実行できます。Inferentiaでボックス外で変換できるモデルに関する詳細情報は、Neuronドキュメンテーションの [Model Architecture Fit](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/models/models-inferentia.html#models-inferentia) セクションにあります。
+
+### Dependencies
+
+モデルをAWS Neuronに変換するには、[Neuron SDK 環境](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/neuron-frameworks/pytorch-neuron/index.html#installation-guide) が必要で、[AWS Deep Learning AMI](https://docs.aws.amazon.com/dlami/latest/devguide/tutorial-inferentia-launching.html) に事前に構成されています。
+
+### Converting a model for AWS Neuron
+
+モデルをAWS NEURON用に変換するには、[PythonでTorchScriptを使用する](torchscript#using-torchscript-in-python) と同じコードを使用して `BertModel` をトレースします。Python APIを介してNeuron SDKのコンポーネントにアクセスするために、`torch.neuron` フレームワーク拡張をインポートします。
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+import torch.neuron
+```
+
+次の行を変更するだけで済みます。
+
+```diff
+- torch.jit.trace(model, [tokens_tensor, segments_tensors])
++ torch.neuron.trace(model, [token_tensor, segments_tensors])
+```
+
+これにより、Neuron SDKはモデルをトレースし、Inf1インスタンス向けに最適化します。
+
+AWS Neuron SDKの機能、ツール、サンプルチュートリアル、最新のアップデートについて詳しく知りたい場合は、[AWS NeuronSDK ドキュメンテーション](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/index.html) をご覧ください。
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/training.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/training.md
new file mode 100644
index 0000000000000000000000000000000000000000..9dd2369601c10a52f009dc4a790e63d14370b8d0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ja/training.md
@@ -0,0 +1,434 @@
+
+
+# Fine-tune a pretrained model
+
+[[open-in-colab]]
+
+事前学習済みモデルを使用すると、計算コストを削減し、炭素排出量を減少させ、ゼロからモデルをトレーニングする必要なしに最新のモデルを使用できる利点があります。
+🤗 Transformersは、さまざまなタスクに対応した数千もの事前学習済みモデルへのアクセスを提供します。
+事前学習済みモデルを使用する場合、それを特定のタスクに合わせたデータセットでトレーニングします。これはファインチューニングとして知られ、非常に強力なトレーニング技術です。
+このチュートリアルでは、事前学習済みモデルを選択したディープラーニングフレームワークでファインチューニングする方法について説明します:
+
+* 🤗 Transformersの[`Trainer`]を使用して事前学習済みモデルをファインチューニングする。
+* TensorFlowとKerasを使用して事前学習済みモデルをファインチューニングする。
+* ネイティブのPyTorchを使用して事前学習済みモデルをファインチューニングする。
+
+
+
+
+
+一部の事前学習済みの重みが使用されず、一部の重みがランダムに初期化された警告が表示されることがあります。心配しないでください、これは完全に正常です!
+BERTモデルの事前学習済みのヘッドは破棄され、ランダムに初期化された分類ヘッドで置き換えられます。この新しいモデルヘッドをシーケンス分類タスクでファインチューニングし、事前学習モデルの知識をそれに転送します。
+
+
+
+### Training Hyperparameters
+
+次に、トレーニングオプションをアクティベートするためのすべてのハイパーパラメータと、調整できるハイパーパラメータを含む[`TrainingArguments`]クラスを作成します。
+このチュートリアルでは、デフォルトのトレーニング[ハイパーパラメータ](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments)を使用して開始できますが、最適な設定を見つけるためにこれらを実験しても構いません。
+
+トレーニングのチェックポイントを保存する場所を指定します:
+
+```python
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(output_dir="test_trainer")
+```
+
+### Evaluate
+
+[`Trainer`]はトレーニング中に自動的にモデルのパフォーマンスを評価しません。メトリクスを計算して報告する関数を[`Trainer`]に渡す必要があります。
+[🤗 Evaluate](https://huggingface.co/docs/evaluate/index)ライブラリでは、[`evaluate.load`]関数を使用して読み込むことができるシンプルな[`accuracy`](https://huggingface.co/spaces/evaluate-metric/accuracy)関数が提供されています(詳細については[こちらのクイックツアー](https://huggingface.co/docs/evaluate/a_quick_tour)を参照してください):
+
+```python
+>>> import numpy as np
+>>> import evaluate
+
+>>> metric = evaluate.load("accuracy")
+```
+
+`metric`の`~evaluate.compute`を呼び出して、予測の正確度を計算します。 `compute`に予測を渡す前に、予測をロジットに変換する必要があります(すべての🤗 Transformersモデルはロジットを返すことを覚えておいてください):
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... predictions = np.argmax(logits, axis=-1)
+... return metric.compute(predictions=predictions, references=labels)
+```
+
+評価メトリクスをファインチューニング中に監視したい場合、トレーニング引数で `eval_strategy` パラメータを指定して、各エポックの終了時に評価メトリクスを報告します:
+
+```python
+>>> from transformers import TrainingArguments, Trainer
+
+>>> training_args = TrainingArguments(output_dir="test_trainer", eval_strategy="epoch")
+```
+
+### Trainer
+
+モデル、トレーニング引数、トレーニングおよびテストデータセット、評価関数を使用して[`Trainer`]オブジェクトを作成します:
+
+```py
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... )
+```
+
+その後、[`~transformers.Trainer.train`]を呼び出してモデルを微調整します:
+
+```python
+>>> trainer.train()
+```
+
+
+
+
+
+モデルを`compile()`する際に`loss`引数を渡す必要はありません!Hugging Faceモデルは、この引数を空白のままにしておくと、タスクとモデルアーキテクチャに適した損失を自動的に選択します。
+必要に応じて自分で損失を指定してオーバーライドすることもできます!
+
+
+
+このアプローチは、小規模なデータセットには適していますが、大規模なデータセットに対しては問題になることがあります。なぜなら、トークナイズされた配列とラベルはメモリに完全に読み込まれる必要があり、またNumPyは「ジャギー」な配列を処理しないため、トークナイズされた各サンプルを全体のデータセット内で最も長いサンプルの長さにパディングする必要があります。
+これにより、配列がさらに大きくなり、すべてのパディングトークンがトレーニングを遅くする原因になります!
+
+### Loading data as a tf.data.Dataset
+
+トレーニングを遅くせずにデータを読み込むには、データを`tf.data.Dataset`として読み込むことができます。独自の`tf.data`パイプラインを作成することもできますが、これを行うための便利な方法が2つあります:
+
+- [`~TFPreTrainedModel.prepare_tf_dataset`]: これはほとんどの場合で推奨する方法です。モデル上のメソッドなので、モデルを検査してモデル入力として使用可能な列を自動的に把握し、他の列を破棄してより単純で高性能なデータセットを作成できます。
+- [`~datasets.Dataset.to_tf_dataset`]: このメソッドはより低レベルで、データセットがどのように作成されるかを正確に制御する場合に便利です。`columns`と`label_cols`を指定して、データセットに含める列を正確に指定できます。
+
+[`~TFPreTrainedModel.prepare_tf_dataset`]を使用する前に、次のコードサンプルに示すように、トークナイザの出力をデータセットに列として追加する必要があります:
+
+```py
+def tokenize_dataset(data):
+ # 返された辞書のキーはデータセットに列として追加されます
+ return tokenizer(data["text"])
+
+
+dataset = dataset.map(tokenize_dataset)
+```
+
+Hugging Faceのデータセットはデフォルトでディスクに保存されるため、これによりメモリの使用量が増えることはありません!
+列が追加されたら、データセットからバッチをストリームし、各バッチにパディングを追加できます。これにより、
+データセット全体にパディングを追加する場合と比べて、パディングトークンの数が大幅に削減されます。
+
+```python
+>>> tf_dataset = model.prepare_tf_dataset(dataset["train"], batch_size=16, shuffle=True, tokenizer=tokenizer)
+```
+
+上記のコードサンプルでは、トークナイザを`prepare_tf_dataset`に渡して、バッチを正しく読み込む際に正しくパディングできるようにする必要があります。
+データセットのすべてのサンプルが同じ長さであり、パディングが不要な場合は、この引数をスキップできます。
+パディング以外の複雑な処理を行う必要がある場合(例:マスク言語モデリングのためのトークンの破損など)、
+代わりに`collate_fn`引数を使用して、サンプルのリストをバッチに変換し、必要な前処理を適用する関数を渡すことができます。
+このアプローチを実際に使用した例については、
+[examples](https://github.com/huggingface/transformers/tree/main/examples)や
+[notebooks](https://huggingface.co/docs/transformers/notebooks)をご覧ください。
+
+`tf.data.Dataset`を作成したら、以前と同様にモデルをコンパイルし、適合させることができます:
+
+```python
+model.compile(optimizer=Adam(3e-5)) # 損失引数は不要です!
+
+model.fit(tf_dataset)
+```
+
+
+
+
+
+
+
+
+クラウドGPUが利用できない場合、[Colaboratory](https://colab.research.google.com/)や[SageMaker StudioLab](https://studiolab.sagemaker.aws/)などのホストされたノートブックを使用して無料でGPUにアクセスできます。
+
+
+
+さて、トレーニングの準備が整いました! 🥳
+
+### トレーニングループ
+
+トレーニングの進捗を追跡するために、[tqdm](https://tqdm.github.io/)ライブラリを使用してトレーニングステップの数に対して進行状況バーを追加します:
+
+```py
+>>> from tqdm.auto import tqdm
+
+>>> progress_bar = tqdm(range(num_training_steps))
+
+>>> model.train()
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... outputs = model(**batch)
+... loss = outputs.loss
+... loss.backward()
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+### Evaluate
+
+[`Trainer`]に評価関数を追加したのと同様に、独自のトレーニングループを作成する際にも同様の操作を行う必要があります。
+ただし、各エポックの最後にメトリックを計算および報告する代わりに、今回は[`~evaluate.add_batch`]を使用してすべてのバッチを蓄積し、最後にメトリックを計算します。
+
+```python
+>>> import evaluate
+
+>>> metric = evaluate.load("accuracy")
+>>> model.eval()
+>>> for batch in eval_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... with torch.no_grad():
+... outputs = model(**batch)
+
+... logits = outputs.logits
+... predictions = torch.argmax(logits, dim=-1)
+... metric.add_batch(predictions=predictions, references=batch["labels"])
+
+>>> metric.compute()
+```
+
+
+
+
+
+
+Transformers Agentsは、いつでも変更される可能性のある実験的なAPIです。エージェントが返す結果は、APIまたは基礎となるモデルが変更される可能性があるため、異なることがあります。
+
+
+
+Transformersバージョンv4.29.0は、*ツール*と*エージェント*のコンセプトを基に構築されています。この[colab](https://colab.research.google.com/drive/1c7MHD-T1forUPGcC_jlwsIptOzpG3hSj)で試すことができます。
+
+要するに、これはtransformersの上に自然言語APIを提供するものです:私たちは一連の厳選されたツールを定義し、自然言語を解釈し、これらのツールを使用するエージェントを設計します。これは設計上拡張可能です。私たちはいくつかの関連するツールを厳選しましたが、コミュニティによって開発された任意のツールを使用するためにシステムを簡単に拡張できる方法も示します。
+
+この新しいAPIで何ができるかのいくつかの例から始めましょう。特に多モーダルなタスクに関して強力ですので、画像を生成したりテキストを読み上げたりするのに最適です。
+
+上記のテキストの上に、日本語の翻訳を提供します。
+
+
+```py
+agent.run("Caption the following image", image=image)
+```
+
+| **Input** | **Output** |
+|-----------------------------------------------------------------------------------------------------------------------------|-----------------------------------|
+| your browser does not support the audio element. ")
+```
+
+BigCodeまたはOpenAssistantを使用するには、まずログインしてInference APIにアクセスしてください。
+
+```py
+from huggingface_hub import login
+
+login("")
+```
+
+次に、エージェントをインスタンス化してください。
+
+```py
+from transformers import HfAgent
+
+# Starcoder
+agent = HfAgent("https://api-inference.huggingface.co/models/bigcode/starcoder")
+# StarcoderBase
+# agent = HfAgent("https://api-inference.huggingface.co/models/bigcode/starcoderbase")
+# OpenAssistant
+# agent = HfAgent(url_endpoint="https://api-inference.huggingface.co/models/OpenAssistant/oasst-sft-4-pythia-12b-epoch-3.5")
+```
+
+これは、Hugging Faceが現在無料で提供している推論APIを使用しています。このモデル(または別のモデル)の独自の推論エンドポイントをお持ちの場合は、上記のURLエンドポイントをご自分のURLエンドポイントで置き換えることができます。
+
+
+
+StarCoderとOpenAssistantは無料で利用でき、シンプルなタスクには非常に優れた性能を発揮します。ただし、より複雑なプロンプトを処理する際には、チェックポイントが十分でないことがあります。そのような場合には、現時点ではオープンソースではないものの、パフォーマンスが向上する可能性のあるOpenAIモデルを試してみることをお勧めします。
+
+
+
+これで準備が整いました!これから、あなたが利用できる2つのAPIについて詳しく説明します。
+
+### Single execution (run)
+
+単一実行メソッドは、エージェントの [`~Agent.run`] メソッドを使用する場合です。
+
+
+```py
+agent.run("Draw me a picture of rivers and lakes.")
+```
+
+
+
+これは、モデルがあなたのリクエストを理解できない場合や、ツールを混同する場合に役立つことがあります。例えば:
+
+```py
+agent.run("Draw me the picture of a capybara swimming in the sea")
+```
+
+ここでは、モデルは2つの方法で解釈できます:
+- `text-to-image`に海で泳ぐカピバラを生成させる
+- または、`text-to-image`でカピバラを生成し、それを海で泳がせるために`image-transformation`ツールを使用する
+
+最初のシナリオを強制したい場合は、プロンプトを引数として渡すことができます:
+
+
+```py
+agent.run("Draw me a picture of the `prompt`", prompt="a capybara swimming in the sea")
+```
+
+
+
+
+### Chat-based execution (チャット)
+
+エージェントは、[`~Agent.chat`] メソッドを使用することで、チャットベースのアプローチも可能です。
+
+
+
+メモリ節約のテクニックについての詳細は、[ガイド](performance)を参照してください。
+
+
+
+## Unable to load a saved TensorFlow model
+
+TensorFlowの[model.save](https://www.tensorflow.org/tutorials/keras/save_and_load#save_the_entire_model)メソッドは、モデル全体 - アーキテクチャ、重み、トレーニング設定 - を1つのファイルに保存します。しかし、モデルファイルを再度読み込む際にエラーが発生することがあります。これは、🤗 Transformersがモデルファイル内のすべてのTensorFlow関連オブジェクトを読み込まないためです。TensorFlowモデルの保存と読み込みに関する問題を回避するために、次のことをお勧めします:
+
+- モデルの重みを`h5`ファイル拡張子で保存し、[`~TFPreTrainedModel.from_pretrained`]を使用してモデルを再読み込みする:
+
+```py
+>>> from transformers import TFPreTrainedModel
+
+>>> model.save_weights("some_folder/tf_model.h5")
+>>> model = TFPreTrainedModel.from_pretrained("some_folder")
+```
+
+- Save the model with [`~TFPretrainedModel.save_pretrained`] and load it again with [`~TFPreTrainedModel.from_pretrained`]:
+
+```py
+>>> from transformers import TFPreTrainedModel
+
+>>> model.save_pretrained("path_to/model")
+>>> model = TFPreTrainedModel.from_pretrained("path_to/model")
+```
+
+## ImportError
+
+もう一つよくあるエラーは、特に新しくリリースされたモデルの場合に遭遇することがある `ImportError` です:
+
+
+```
+ImportError: cannot import name 'ImageGPTImageProcessor' from 'transformers' (unknown location)
+```
+
+これらのエラータイプに関しては、最新バージョンの 🤗 Transformers がインストールされていることを確認して、最新のモデルにアクセスできるようにしてください:
+
+```bash
+pip install transformers --upgrade
+```
+
+## CUDA error: device-side assert triggered
+
+時々、デバイスコードでエラーが発生したという一般的な CUDA エラーに遭遇することがあります。
+
+```
+RuntimeError: CUDA error: device-side assert triggered
+```
+
+より具体的なエラーメッセージを取得するために、まずはCPU上でコードを実行してみることをお勧めします。以下の環境変数をコードの冒頭に追加して、CPUに切り替えてみてください:
+
+```py
+>>> import os
+
+>>> os.environ["CUDA_VISIBLE_DEVICES"] = ""
+```
+
+GPUからより良いトレースバックを取得する別のオプションは、次の環境変数をコードの先頭に追加することです。これにより、エラーの発生源を指すトレースバックが得られます:
+
+```py
+>>> import os
+
+>>> os.environ["CUDA_LAUNCH_BLOCKING"] = "1"
+```
+
+
+## Incorrect output when padding tokens aren't masked
+
+一部のケースでは、`input_ids`にパディングトークンが含まれている場合、出力の`hidden_state`が正しくないことがあります。デモンストレーションのために、モデルとトークナイザーをロードします。モデルの`pad_token_id`にアクセスして、その値を確認できます。一部のモデルでは`pad_token_id`が`None`になることもありますが、常に手動で設定することができます。
+
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+>>> import torch
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-uncased")
+>>> model.config.pad_token_id
+0
+```
+
+以下の例は、パディングトークンをマスクせずに出力を表示したものです:
+
+```py
+>>> input_ids = torch.tensor([[7592, 2057, 2097, 2393, 9611, 2115], [7592, 0, 0, 0, 0, 0]])
+>>> output = model(input_ids)
+>>> print(output.logits)
+tensor([[ 0.0082, -0.2307],
+ [ 0.1317, -0.1683]], grad_fn=)
+```
+
+以下は、第2のシーケンスの実際の出力です:
+
+```py
+>>> input_ids = torch.tensor([[7592]])
+>>> output = model(input_ids)
+>>> print(output.logits)
+tensor([[-0.1008, -0.4061]], grad_fn=)
+```
+
+大抵の場合、モデルには `attention_mask` を提供して、パディングトークンを無視し、このような無音のエラーを回避する必要があります。これにより、2番目のシーケンスの出力が実際の出力と一致するようになります。
+
+
+
+デフォルトでは、トークナイザは、トークナイザのデフォルトに基づいて `attention_mask` を自動で作成します。
+
+
+
+```py
+>>> attention_mask = torch.tensor([[1, 1, 1, 1, 1, 1], [1, 0, 0, 0, 0, 0]])
+>>> output = model(input_ids, attention_mask=attention_mask)
+>>> print(output.logits)
+tensor([[ 0.0082, -0.2307],
+ [-0.1008, -0.4061]], grad_fn=)
+```
+
+🤗 Transformersは、提供されるパディングトークンをマスクするために自動的に`attention_mask`を作成しません。その理由は以下の通りです:
+
+- 一部のモデルにはパディングトークンが存在しない場合があるためです。
+- 一部のユースケースでは、ユーザーがパディングトークンにアテンションを向けることを望む場合があるためです。
+
+## ValueError: Unrecognized configuration class XYZ for this kind of AutoModel
+
+一般的に、事前学習済みモデルのインスタンスをロードするためには[`AutoModel`]クラスを使用することをお勧めします。このクラスは、設定に基づいて与えられたチェックポイントから正しいアーキテクチャを自動的に推測およびロードできます。モデルをロードする際にこの`ValueError`が表示される場合、Autoクラスは与えられたチェックポイントの設定から、ロードしようとしているモデルの種類へのマッピングを見つけることができなかったことを意味します。最も一般的には、特定のタスクをサポートしないチェックポイントがある場合にこのエラーが発生します。
+例えば、質問応答のためのGPT2が存在しない場合、次の例でこのエラーが表示されます:
+
+上記のテキストを日本語に翻訳し、Markdownファイルとしてフォーマットしました。
+
+
+```py
+>>> from transformers import AutoProcessor, AutoModelForQuestionAnswering
+
+>>> processor = AutoProcessor.from_pretrained("openai-community/gpt2-medium")
+>>> model = AutoModelForQuestionAnswering.from_pretrained("openai-community/gpt2-medium")
+ValueError: Unrecognized configuration class for this kind of AutoModel: AutoModelForQuestionAnswering.
+Model type should be one of AlbertConfig, BartConfig, BertConfig, BigBirdConfig, BigBirdPegasusConfig, BloomConfig, ...
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/_config.py b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/_config.py
new file mode 100644
index 0000000000000000000000000000000000000000..ab61af6ef9e86028ae075e01fb244ae4226f387b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/_config.py
@@ -0,0 +1,14 @@
+# docstyle-ignore
+INSTALL_CONTENT = """
+# Transformers 설치 방법
+! pip install transformers datasets evaluate accelerate
+# 마지막 릴리스 대신 소스에서 설치하려면, 위 명령을 주석으로 바꾸고 아래 명령을 해제하세요.
+# ! pip install git+https://github.com/huggingface/transformers.git
+"""
+
+notebook_first_cells = [{"type": "code", "content": INSTALL_CONTENT}]
+black_avoid_patterns = {
+ "{processor_class}": "FakeProcessorClass",
+ "{model_class}": "FakeModelClass",
+ "{object_class}": "FakeObjectClass",
+}
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/_toctree.yml b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..dfa50f9f13a1f138a545909ee3c35c5190aa9d62
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/_toctree.yml
@@ -0,0 +1,792 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers
+ - local: quicktour
+ title: 둘러보기
+ - local: installation
+ title: 설치방법
+ title: 시작하기
+- sections:
+ - local: pipeline_tutorial
+ title: Pipeline으로 추론하기
+ - local: autoclass_tutorial
+ title: AutoClass로 사전 학습된 인스턴스 로드하기
+ - local: preprocessing
+ title: 데이터 전처리하기
+ - local: training
+ title: 사전 학습된 모델 미세 조정하기
+ - local: run_scripts
+ title: 스크립트로 학습하기
+ - local: accelerate
+ title: 🤗 Accelerate로 분산 학습 구성하기
+ - local: peft
+ title: 🤗 PEFT로 어댑터 로드 및 학습하기
+ - local: model_sharing
+ title: 만든 모델 공유하기
+ - local: transformers_agents
+ title: 에이전트
+ - local: llm_tutorial
+ title: 대규모 언어 모델로 생성하기
+ - local: conversations
+ title: Transformers로 채팅하기
+ title: 튜토리얼
+- sections:
+ - isExpanded: false
+ sections:
+ - local: tasks/sequence_classification
+ title: 텍스트 분류
+ - local: tasks/token_classification
+ title: 토큰 분류
+ - local: tasks/question_answering
+ title: 질의 응답(Question Answering)
+ - local: tasks/language_modeling
+ title: 인과적 언어 모델링(Causal language modeling)
+ - local: tasks/masked_language_modeling
+ title: 마스킹된 언어 모델링(Masked language modeling)
+ - local: tasks/translation
+ title: 번역
+ - local: tasks/summarization
+ title: 요약
+ - local: tasks/multiple_choice
+ title: 객관식 문제(Multiple Choice)
+ title: 자연어처리
+ - isExpanded: false
+ sections:
+ - local: tasks/audio_classification
+ title: 오디오 분류
+ - local: tasks/asr
+ title: 자동 음성 인식
+ title: 오디오
+ - isExpanded: false
+ sections:
+ - local: tasks/image_classification
+ title: 이미지 분류
+ - local: tasks/semantic_segmentation
+ title: 의미적 분할(Semantic segmentation)
+ - local: tasks/video_classification
+ title: 영상 분류
+ - local: tasks/object_detection
+ title: 객체 탐지
+ - local: tasks/zero_shot_object_detection
+ title: 제로샷(zero-shot) 객체 탐지
+ - local: tasks/zero_shot_image_classification
+ title: 제로샷(zero-shot) 이미지 분류
+ - local: tasks/monocular_depth_estimation
+ title: 단일 영상 기반 깊이 추정
+ - local: tasks/image_to_image
+ title: Image-to-Image
+ - local: tasks/image_feature_extraction
+ title: 이미지 특징 추출
+ - local: tasks/mask_generation
+ title: 마스크 생성
+ - local: tasks/knowledge_distillation_for_image_classification
+ title: 컴퓨터 비전(이미지 분류)를 위한 지식 증류(knowledge distillation)
+ title: 컴퓨터 비전
+ - isExpanded: false
+ sections:
+ - local: tasks/image_captioning
+ title: 이미지 캡셔닝
+ - local: tasks/document_question_answering
+ title: 문서 질의 응답(Document Question Answering)
+ - local: tasks/visual_question_answering
+ title: 시각적 질의응답 (Visual Question Answering)
+ - local: in_translation
+ title: (번역중) Text to speech
+ title: 멀티모달
+ - isExpanded: false
+ sections:
+ - local: generation_strategies
+ title: 텍스트 생성 전략 사용자 정의
+ title: 생성
+ - isExpanded: false
+ sections:
+ - local: tasks/idefics
+ title: IDEFICS를 이용한 이미지 작업
+ - local: tasks/prompting
+ title: 대규모 언어 모델 프롬프팅 가이드
+ title: 프롬프팅
+ title: 태스크 가이드
+- sections:
+ - local: fast_tokenizers
+ title: 🤗 Tokenizers 라이브러리에서 토크나이저 사용하기
+ - local: multilingual
+ title: 다국어 모델 추론하기
+ - local: create_a_model
+ title: 모델별 API 사용하기
+ - local: custom_models
+ title: 사용자 정의 모델 공유하기
+ - local: chat_templating
+ title: 챗봇 템플릿 익히기
+ - local: trainer
+ title: Trainer 사용하기
+ - local: sagemaker
+ title: Amazon SageMaker에서 학습 실행하기
+ - local: serialization
+ title: ONNX로 내보내기
+ - local: tflite
+ title: TFLite로 내보내기
+ - local: torchscript
+ title: TorchScript로 내보내기
+ - local: in_translation
+ title: (번역중) Benchmarks
+ - local: in_translation
+ title: (번역중) Notebooks with examples
+ - local: community
+ title: 커뮤니티 리소스
+ - local: troubleshooting
+ title: 문제 해결
+ - local: gguf
+ title: GGUF 파일들과의 상호 운용성
+ - local: modular_transformers
+ title: transformers에서의 모듈성
+ title: (번역중) 개발자 가이드
+- sections:
+ - local: in_translation
+ title: (번역중) Getting started
+ - local: quantization/bitsandbytes
+ title: bitsandbytes
+ - local: quantization/gptq
+ title: GPTQ
+ - local: quantization/awq
+ title: AWQ
+ - local: in_translation
+ title: (번역중) AQLM
+ - local: in_translation
+ title: (번역중) VPTQ
+ - local: quantization/quanto
+ title: Quanto
+ - local: quantization/eetq
+ title: EETQ
+ - local: in_translation
+ title: (번역중) HQQ
+ - local: in_translation
+ title: (번역중) Optimum
+ - local: in_translation
+ title: (번역중) Contribute new quantization method
+ title: (번역중) 경량화 메소드
+- sections:
+ - local: performance
+ title: 성능 및 확장성
+ - local: in_translation
+ title: (번역중) Quantization
+ - local: llm_optims
+ title: LLM 추론 최적화
+ - sections:
+ - local: in_translation
+ title: (번역중) Methods and tools for efficient training on a single GPU
+ - local: perf_train_gpu_many
+ title: 다중 GPU에서 훈련 진행하기
+ - local: deepspeed
+ title: DeepSpeed
+ - local: fsdp
+ title: 완전 분할 데이터 병렬 처리
+ - local: perf_train_cpu
+ title: CPU에서 훈련
+ - local: perf_train_cpu_many
+ title: 다중 CPU에서 훈련하기
+ - local: perf_train_tpu_tf
+ title: TensorFlow로 TPU에서 훈련하기
+ - local: perf_train_special
+ title: Apple 실리콘에서 PyTorch 학습
+ - local: perf_hardware
+ title: 훈련용 사용자 맞춤형 하드웨어
+ - local: hpo_train
+ title: Trainer API를 사용한 하이퍼파라미터 탐색
+ title: (번역중) 효율적인 학습 기술들
+ - sections:
+ - local: perf_infer_cpu
+ title: CPU로 추론하기
+ - local: perf_infer_gpu_one
+ title: 하나의 GPU를 활용한 추론
+ title: 추론 최적화하기
+ - local: big_models
+ title: 대형 모델을 인스턴스화
+ - local: debugging
+ title: 디버깅
+ - local: tf_xla
+ title: TensorFlow 모델을 위한 XLA 통합
+ - local: in_translation
+ title: (번역중) Optimize inference using `torch.compile()`
+ title: (번역중) 성능 및 확장성
+- sections:
+ - local: contributing
+ title: 🤗 Transformers에 기여하는 방법
+ - local: add_new_model
+ title: 🤗 Transformers에 새로운 모델을 추가하는 방법
+ - local: add_new_pipeline
+ title: 어떻게 🤗 Transformers에 파이프라인을 추가하나요?
+ - local: testing
+ title: 테스트
+ - local: pr_checks
+ title: Pull Request에 대한 검사
+ title: 기여하기
+- sections:
+ - local: philosophy
+ title: 이념과 목표
+ - local: in_translation
+ title: (번역중) Glossary
+ - local: task_summary
+ title: 🤗 Transformers로 할 수 있는 작업
+ - local: tasks_explained
+ title: 🤗 Transformers로 작업을 해결하는 방법
+ - local: model_summary
+ title: Transformer 모델군
+ - local: tokenizer_summary
+ title: 토크나이저 요약
+ - local: attention
+ title: 어텐션 매커니즘
+ - local: pad_truncation
+ title: 패딩과 잘라내기
+ - local: bertology
+ title: BERTology
+ - local: perplexity
+ title: 고정 길이 모델의 펄플렉서티(Perplexity)
+ - local: pipeline_webserver
+ title: 추론 웹 서버를 위한 파이프라인
+ - local: model_memory_anatomy
+ title: 모델 학습 해부하기
+ - local: llm_tutorial_optimization
+ title: LLM을 최대한 활용하기
+ title: (번역중) 개념 가이드
+- sections:
+ - sections:
+ - local: main_classes/agent
+ title: 에이전트와 도구
+ - local: model_doc/auto
+ title: 자동 클래스
+ - local: in_translation
+ title: (번역중) Backbones
+ - local: main_classes/callback
+ title: 콜백
+ - local: main_classes/configuration
+ title: 구성
+ - local: main_classes/data_collator
+ title: 데이터 콜레이터
+ - local: main_classes/keras_callbacks
+ title: 케라스 콜백
+ - local: main_classes/logging
+ title: 로깅
+ - local: main_classes/model
+ title: Models
+ - local: main_classes/text_generation
+ title: 텍스트 생성
+ - local: main_classes/onnx
+ title: ONNX
+ - local: in_translation
+ title: (번역중) Optimization
+ - local: in_translation
+ title: 모델 출력
+ - local: main_classes/output
+ title: (번역중) Pipelines
+ - local: in_translation
+ title: (번역중) Processors
+ - local: main_classes/quantization
+ title: 양자화
+ - local: in_translation
+ title: (번역중) Tokenizer
+ - local: main_classes/trainer
+ title: Trainer
+ - local: deepspeed
+ title: DeepSpeed
+ - local: main_classes/executorch
+ title: ExecuTorch
+ - local: main_classes/feature_extractor
+ title: 특성 추출기
+ - local: in_translation
+ title: (번역중) Image Processor
+ title: (번역중) 메인 클래스
+ - sections:
+ - isExpanded: false
+ sections:
+ - local: in_translation
+ title: (번역중) ALBERT
+ - local: model_doc/bart
+ title: BART
+ - local: model_doc/barthez
+ title: BARThez
+ - local: model_doc/bartpho
+ title: BARTpho
+ - local: model_doc/bert
+ title: BERT
+ - local: in_translation
+ title: (번역중) BertGeneration
+ - local: model_doc/bert-japanese
+ title: 일본어 Bert
+ - local: model_doc/bertweet
+ title: Bertweet
+ - local: in_translation
+ title: (번역중) BigBird
+ - local: in_translation
+ title: (번역중) BigBirdPegasus
+ - local: model_doc/biogpt
+ title: BioGpt
+ - local: in_translation
+ title: (번역중) Blenderbot
+ - local: in_translation
+ title: (번역중) Blenderbot Small
+ - local: in_translation
+ title: (번역중) BLOOM
+ - local: in_translation
+ title: (번역중) BORT
+ - local: in_translation
+ title: (번역중) ByT5
+ - local: in_translation
+ title: (번역중) CamemBERT
+ - local: in_translation
+ title: (번역중) CANINE
+ - local: in_translation
+ title: (번역중) CodeGen
+ - local: model_doc/cohere
+ title: Cohere
+ - local: model_doc/convbert
+ title: ConvBERT
+ - local: in_translation
+ title: (번역중) CPM
+ - local: in_translation
+ title: (번역중) CPMANT
+ - local: in_translation
+ title: (번역중) CTRL
+ - local: model_doc/dbrx
+ title: DBRX
+ - local: model_doc/deberta
+ title: DeBERTa
+ - local: model_doc/deberta-v2
+ title: DeBERTa-v2
+ - local: in_translation
+ title: (번역중) DialoGPT
+ - local: in_translation
+ title: (번역중) DistilBERT
+ - local: in_translation
+ title: (번역중) DPR
+ - local: in_translation
+ title: (번역중) ELECTRA
+ - local: model_doc/encoder-decoder
+ title: 인코더 디코더 모델
+ - local: in_translation
+ title: (번역중) ERNIE
+ - local: in_translation
+ title: (번역중) ErnieM
+ - local: model_doc/esm
+ title: ESM
+ - local: in_translation
+ title: (번역중) FLAN-T5
+ - local: in_translation
+ title: (번역중) FLAN-UL2
+ - local: in_translation
+ title: (번역중) FlauBERT
+ - local: in_translation
+ title: (번역중) FNet
+ - local: in_translation
+ title: (번역중) FSMT
+ - local: in_translation
+ title: (번역중) Funnel Transformer
+ - local: model_doc/gemma
+ title: Gemma
+ - local: model_doc/gemma2
+ title: Gemma2
+ - local: model_doc/openai-gpt
+ title: GPT
+ - local: in_translation
+ title: (번역중) GPT Neo
+ - local: in_translation
+ title: (번역중) GPT NeoX
+ - local: model_doc/gpt_neox_japanese
+ title: GPT NeoX Japanese
+ - local: in_translation
+ title: (번역중) GPT-J
+ - local: in_translation
+ title: (번역중) GPT2
+ - local: in_translation
+ title: (번역중) GPTBigCode
+ - local: in_translation
+ title: (번역중) GPTSAN Japanese
+ - local: in_translation
+ title: (번역중) GPTSw3
+ - local: in_translation
+ title: (번역중) HerBERT
+ - local: in_translation
+ title: (번역중) I-BERT
+ - local: in_translation
+ title: (번역중) Jukebox
+ - local: in_translation
+ title: (번역중) LED
+ - local: model_doc/llama
+ title: LLaMA
+ - local: model_doc/llama2
+ title: LLaMA2
+ - local: model_doc/llama3
+ title: LLaMA3
+ - local: in_translation
+ title: (번역중) Longformer
+ - local: in_translation
+ title: (번역중) LongT5
+ - local: in_translation
+ title: (번역중) LUKE
+ - local: in_translation
+ title: (번역중) M2M100
+ - local: model_doc/mamba
+ title: Mamba
+ - local: model_doc/mamba2
+ title: Mamba2
+ - local: model_doc/marian
+ title: MarianMT
+ - local: in_translation
+ title: (번역중) MarkupLM
+ - local: in_translation
+ title: (번역중) MBart and MBart-50
+ - local: in_translation
+ title: (번역중) MEGA
+ - local: in_translation
+ title: (번역중) MegatronBERT
+ - local: in_translation
+ title: (번역중) MegatronGPT2
+ - local: model_doc/mistral
+ title: Mistral
+ - local: in_translation
+ title: (번역중) mLUKE
+ - local: in_translation
+ title: (번역중) MobileBERT
+ - local: in_translation
+ title: (번역중) MPNet
+ - local: in_translation
+ title: (번역중) MT5
+ - local: in_translation
+ title: (번역중) MVP
+ - local: in_translation
+ title: (번역중) NEZHA
+ - local: in_translation
+ title: (번역중) NLLB
+ - local: in_translation
+ title: (번역중) NLLB-MoE
+ - local: in_translation
+ title: (번역중) Nyströmformer
+ - local: in_translation
+ title: (번역중) Open-Llama
+ - local: in_translation
+ title: (번역중) OPT
+ - local: in_translation
+ title: (번역중) Pegasus
+ - local: in_translation
+ title: (번역중) PEGASUS-X
+ - local: in_translation
+ title: (번역중) PhoBERT
+ - local: in_translation
+ title: (번역중) PLBart
+ - local: in_translation
+ title: (번역중) ProphetNet
+ - local: in_translation
+ title: (번역중) QDQBert
+ - local: model_doc/rag
+ title: RAG(검색 증강 생성)
+ - local: in_translation
+ title: (번역중) REALM
+ - local: in_translation
+ title: (번역중) Reformer
+ - local: in_translation
+ title: (번역중) RemBERT
+ - local: in_translation
+ title: (번역중) RetriBERT
+ - local: in_translation
+ title: (번역중) RoBERTa
+ - local: in_translation
+ title: (번역중) RoBERTa-PreLayerNorm
+ - local: in_translation
+ title: (번역중) RoCBert
+ - local: in_translation
+ title: (번역중) RoFormer
+ - local: in_translation
+ title: (번역중) Splinter
+ - local: in_translation
+ title: (번역중) SqueezeBERT
+ - local: in_translation
+ title: (번역중) SwitchTransformers
+ - local: in_translation
+ title: (번역중) T5
+ - local: in_translation
+ title: (번역중) T5v1.1
+ - local: in_translation
+ title: (번역중) TAPEX
+ - local: in_translation
+ title: (번역중) Transformer XL
+ - local: in_translation
+ title: (번역중) UL2
+ - local: in_translation
+ title: (번역중) X-MOD
+ - local: in_translation
+ title: (번역중) XGLM
+ - local: in_translation
+ title: (번역중) XLM
+ - local: in_translation
+ title: (번역중) XLM-ProphetNet
+ - local: in_translation
+ title: (번역중) XLM-RoBERTa
+ - local: in_translation
+ title: (번역중) XLM-RoBERTa-XL
+ - local: in_translation
+ title: (번역중) XLM-V
+ - local: in_translation
+ title: (번역중) XLNet
+ - local: in_translation
+ title: (번역중) YOSO
+ title: (번역중) 텍스트 모델
+ - isExpanded: false
+ sections:
+ - local: in_translation
+ title: (번역중) BEiT
+ - local: in_translation
+ title: (번역중) BiT
+ - local: in_translation
+ title: (번역중) Conditional DETR
+ - local: in_translation
+ title: (번역중) ConvNeXT
+ - local: in_translation
+ title: (번역중) ConvNeXTV2
+ - local: in_translation
+ title: (번역중) CvT
+ - local: in_translation
+ title: (번역중) Deformable DETR
+ - local: in_translation
+ title: (번역중) DeiT
+ - local: in_translation
+ title: (번역중) DETA
+ - local: in_translation
+ title: (번역중) DETR
+ - local: in_translation
+ title: (번역중) DiNAT
+ - local: in_translation
+ title: (번역중) DiT
+ - local: in_translation
+ title: (번역중) DPT
+ - local: in_translation
+ title: (번역중) EfficientFormer
+ - local: in_translation
+ title: (번역중) EfficientNet
+ - local: in_translation
+ title: (번역중) FocalNet
+ - local: in_translation
+ title: (번역중) GLPN
+ - local: in_translation
+ title: (번역중) ImageGPT
+ - local: in_translation
+ title: (번역중) LeViT
+ - local: in_translation
+ title: (번역중) Mask2Former
+ - local: in_translation
+ title: (번역중) MaskFormer
+ - local: in_translation
+ title: (번역중) MobileNetV1
+ - local: in_translation
+ title: (번역중) MobileNetV2
+ - local: in_translation
+ title: (번역중) MobileViT
+ - local: in_translation
+ title: (번역중) NAT
+ - local: in_translation
+ title: (번역중) PoolFormer
+ - local: in_translation
+ title: (번역중) RegNet
+ - local: in_translation
+ title: (번역중) ResNet
+ - local: in_translation
+ title: (번역중) SegFormer
+ - local: model_doc/swin
+ title: Swin Transformer
+ - local: model_doc/swinv2
+ title: Swin Transformer V2
+ - local: model_doc/swin2sr
+ title: Swin2SR
+ - local: in_translation
+ title: (번역중) Table Transformer
+ - local: in_translation
+ title: (번역중) TimeSformer
+ - local: in_translation
+ title: (번역중) UperNet
+ - local: in_translation
+ title: (번역중) VAN
+ - local: in_translation
+ title: (번역중) VideoMAE
+ - local: in_translation
+ title: Vision Transformer (ViT)
+ - local: model_doc/vit
+ title: (번역중) ViT Hybrid
+ - local: in_translation
+ title: (번역중) ViTMAE
+ - local: in_translation
+ title: (번역중) ViTMSN
+ - local: in_translation
+ title: (번역중) YOLOS
+ title: (번역중) 비전 모델
+ - isExpanded: false
+ sections:
+ - local: in_translation
+ title: (번역중) Audio Spectrogram Transformer
+ - local: in_translation
+ title: (번역중) CLAP
+ - local: in_translation
+ title: (번역중) Hubert
+ - local: in_translation
+ title: (번역중) MCTCT
+ - local: in_translation
+ title: (번역중) SEW
+ - local: in_translation
+ title: (번역중) SEW-D
+ - local: in_translation
+ title: (번역중) Speech2Text
+ - local: in_translation
+ title: (번역중) Speech2Text2
+ - local: in_translation
+ title: (번역중) SpeechT5
+ - local: in_translation
+ title: (번역중) UniSpeech
+ - local: in_translation
+ title: (번역중) UniSpeech-SAT
+ - local: in_translation
+ title: (번역중) Wav2Vec2
+ - local: in_translation
+ title: (번역중) Wav2Vec2-Conformer
+ - local: in_translation
+ title: (번역중) Wav2Vec2Phoneme
+ - local: in_translation
+ title: (번역중) WavLM
+ - local: model_doc/whisper
+ title: Whisper
+ - local: in_translation
+ title: (번역중) XLS-R
+ - local: in_translation
+ title: (번역중) XLSR-Wav2Vec2
+ title: (번역중) 오디오 모델
+ - isExpanded: false
+ sections:
+ - local: model_doc/timesformer
+ title: TimeSformer
+ - local: in_translation
+ title: (번역중) VideoMAE
+ - local: model_doc/vivit
+ title: ViViT
+ title: (번역중) 비디오 모델
+ - isExpanded: false
+ sections:
+ - local: in_translation
+ title: (번역중) ALIGN
+ - local: model_doc/altclip
+ title: AltCLIP
+ - local: model_doc/blip-2
+ title: BLIP-2
+ - local: model_doc/blip
+ title: BLIP
+ - local: in_translation
+ title: (번역중) BridgeTower
+ - local: model_doc/chameleon
+ title: Chameleon
+ - local: in_translation
+ title: (번역중) Chinese-CLIP
+ - local: model_doc/clip
+ title: CLIP
+ - local: in_translation
+ title: (번역중) CLIPSeg
+ - local: in_translation
+ title: (번역중) Data2Vec
+ - local: in_translation
+ title: (번역중) DePlot
+ - local: in_translation
+ title: (번역중) Donut
+ - local: in_translation
+ title: (번역중) FLAVA
+ - local: in_translation
+ title: (번역중) GIT
+ - local: in_translation
+ title: (번역중) GroupViT
+ - local: in_translation
+ title: (번역중) LayoutLM
+ - local: in_translation
+ title: (번역중) LayoutLMV2
+ - local: in_translation
+ title: (번역중) LayoutLMV3
+ - local: in_translation
+ title: (번역중) LayoutXLM
+ - local: in_translation
+ title: (번역중) LiLT
+ - local: in_translation
+ title: (번역중) LXMERT
+ - local: in_translation
+ title: (번역중) MatCha
+ - local: in_translation
+ title: (번역중) MGP-STR
+ - local: in_translation
+ title: (번역중) OneFormer
+ - local: in_translation
+ title: (번역중) OWL-ViT
+ - local: model_doc/paligemma
+ title: PaliGemma
+ - local: in_translation
+ title: (번역중) Perceiver
+ - local: in_translation
+ title: (번역중) Pix2Struct
+ - local: in_translation
+ title: (번역중) Segment Anything
+ - local: in_translation
+ title: (번역중) Speech Encoder Decoder Models
+ - local: in_translation
+ title: (번역중) TAPAS
+ - local: in_translation
+ title: (번역중) TrOCR
+ - local: in_translation
+ title: (번역중) TVLT
+ - local: in_translation
+ title: (번역중) ViLT
+ - local: in_translation
+ title: (번역중) Vision Encoder Decoder Models
+ - local: in_translation
+ title: (번역중) Vision Text Dual Encoder
+ - local: in_translation
+ title: (번역중) VisualBERT
+ - local: in_translation
+ title: (번역중) X-CLIP
+ title: (번역중) 멀티모달 모델
+ - isExpanded: false
+ sections:
+ - local: in_translation
+ title: (번역중) Decision Transformer
+ - local: model_doc/trajectory_transformer
+ title: 궤적 트랜스포머
+ title: (번역중) 강화학습 모델
+ - isExpanded: false
+ sections:
+ - local: model_doc/autoformer
+ title: Autoformer
+ - local: model_doc/informer
+ title: Informer
+ - local: model_doc/patchtsmixer
+ title: PatchTSMixer
+ - local: model_doc/patchtst
+ title: PatchTST
+ - local: model_doc/time_series_transformer
+ title: 시계열 트랜스포머
+ title: 시계열 모델
+ - isExpanded: false
+ sections:
+ - local: model_doc/graphormer
+ title: Graphormer
+ title: 그래프 모델
+ title: (번역중) 모델
+ - sections:
+ - local: internal/modeling_utils
+ title: 사용자 정의 레이어 및 유틸리티
+ - local: internal/pipelines_utils
+ title: 파이프라인을 위한 유틸리티
+ - local: internal/tokenization_utils
+ title: 토크나이저를 위한 유틸리티
+ - local: internal/trainer_utils
+ title: Trainer를 위한 유틸리티
+ - local: internal/generation_utils
+ title: 생성을 위한 유틸리티
+ - local: internal/image_processing_utils
+ title: 이미지 프로세서를 위한 유틸리티
+ - local: internal/audio_utils
+ title: 오디오 처리를 위한 유틸리티
+ - local: internal/file_utils
+ title: 일반 유틸리티
+ - local: internal/time_series_utils
+ title: 시계열을 위한 유틸리티
+ title: (번역중) Internal Helpers
+ title: (번역중) API
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/accelerate.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/accelerate.md
new file mode 100644
index 0000000000000000000000000000000000000000..0ef8957de3ac20d38326624d60e7cd1fd349197b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/accelerate.md
@@ -0,0 +1,136 @@
+
+
+# 🤗 Accelerate를 활용한 분산 학습[[distributed-training-with-accelerate]]
+
+모델이 커지면서 병렬 처리는 제한된 하드웨어에서 더 큰 모델을 훈련하고 훈련 속도를 몇 배로 가속화하기 위한 전략으로 등장했습니다. Hugging Face에서는 사용자가 하나의 머신에 여러 개의 GPU를 사용하든 여러 머신에 여러 개의 GPU를 사용하든 모든 유형의 분산 설정에서 🤗 Transformers 모델을 쉽게 훈련할 수 있도록 돕기 위해 [🤗 Accelerate](https://huggingface.co/docs/accelerate) 라이브러리를 만들었습니다. 이 튜토리얼에서는 분산 환경에서 훈련할 수 있도록 기본 PyTorch 훈련 루프를 커스터마이즈하는 방법을 알아봅시다.
+
+## 설정[[setup]]
+
+🤗 Accelerate 설치 시작하기:
+
+```bash
+pip install accelerate
+```
+
+그 다음, [`~accelerate.Accelerator`] 객체를 불러오고 생성합니다. [`~accelerate.Accelerator`]는 자동으로 분산 설정 유형을 감지하고 훈련에 필요한 모든 구성 요소를 초기화합니다. 장치에 모델을 명시적으로 배치할 필요는 없습니다.
+
+```py
+>>> from accelerate import Accelerator
+
+>>> accelerator = Accelerator()
+```
+
+## 가속화를 위한 준비[[prepare-to-accelerate]]
+
+다음 단계는 관련된 모든 훈련 객체를 [`~accelerate.Accelerator.prepare`] 메소드에 전달하는 것입니다. 여기에는 훈련 및 평가 데이터로더, 모델 및 옵티마이저가 포함됩니다:
+
+```py
+>>> train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
+... train_dataloader, eval_dataloader, model, optimizer
+... )
+```
+
+## 백워드(Backward)[[backward]]
+
+마지막으로 훈련 루프의 일반적인 `loss.backward()`를 🤗 Accelerate의 [`~accelerate.Accelerator.backward`] 메소드로 대체하기만 하면 됩니다:
+
+```py
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... outputs = model(**batch)
+... loss = outputs.loss
+... accelerator.backward(loss)
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+다음 코드에서 볼 수 있듯이, 훈련 루프에 코드 네 줄만 추가하면 분산 학습을 활성화할 수 있습니다!
+
+```diff
++ from accelerate import Accelerator
+ from transformers import AdamW, AutoModelForSequenceClassification, get_scheduler
+
++ accelerator = Accelerator()
+
+ model = AutoModelForSequenceClassification.from_pretrained(checkpoint, num_labels=2)
+ optimizer = AdamW(model.parameters(), lr=3e-5)
+
+- device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+- model.to(device)
+
++ train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
++ train_dataloader, eval_dataloader, model, optimizer
++ )
+
+ num_epochs = 3
+ num_training_steps = num_epochs * len(train_dataloader)
+ lr_scheduler = get_scheduler(
+ "linear",
+ optimizer=optimizer,
+ num_warmup_steps=0,
+ num_training_steps=num_training_steps
+ )
+
+ progress_bar = tqdm(range(num_training_steps))
+
+ model.train()
+ for epoch in range(num_epochs):
+ for batch in train_dataloader:
+- batch = {k: v.to(device) for k, v in batch.items()}
+ outputs = model(**batch)
+ loss = outputs.loss
+- loss.backward()
++ accelerator.backward(loss)
+
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ progress_bar.update(1)
+```
+
+## 학습[[train]]
+
+관련 코드를 추가한 후에는 스크립트나 Colaboratory와 같은 노트북에서 훈련을 시작하세요.
+
+### 스크립트로 학습하기[[train-with-a-script]]
+
+스크립트에서 훈련을 실행하는 경우, 다음 명령을 실행하여 구성 파일을 생성하고 저장합니다:
+
+```bash
+accelerate config
+```
+
+Then launch your training with:
+
+```bash
+accelerate launch train.py
+```
+
+### 노트북으로 학습하기[[train-with-a-notebook]]
+
+Collaboratory의 TPU를 사용하려는 경우, 노트북에서도 🤗 Accelerate를 실행할 수 있습니다. 훈련을 담당하는 모든 코드를 함수로 감싸서 [`~accelerate.notebook_launcher`]에 전달하세요:
+
+```py
+>>> from accelerate import notebook_launcher
+
+>>> notebook_launcher(training_function)
+```
+
+🤗 Accelerate 및 다양한 기능에 대한 자세한 내용은 [documentation](https://huggingface.co/docs/accelerate)를 참조하세요.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/add_new_model.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/add_new_model.md
new file mode 100644
index 0000000000000000000000000000000000000000..d5834777d31eefbb00188d11ce1c115557793eab
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/add_new_model.md
@@ -0,0 +1,626 @@
+
+
+# Hugging Face Transformers를 추가하는 방법은 무엇인가요? [[how-to-add-a-model-to-transformers]]
+
+Hugging Face Transformers 라이브러리는 커뮤니티 기여자들 덕분에 새로운 모델을 제공할 수 있는 경우가 많습니다. 하지만 이는 도전적인 프로젝트이며 Hugging Face Transformers 라이브러리와 구현할 모델에 대한 깊은 이해가 필요합니다. Hugging Face에서는 더 많은 커뮤니티 멤버가 모델을 적극적으로 추가할 수 있도록 지원하고자 하며, 이 가이드를 통해 PyTorch 모델을 추가하는 과정을 안내하고 있습니다 (PyTorch가 설치되어 있는지 확인해주세요).
+
+이 과정을 진행하면 다음과 같은 내용을 이해하게 됩니다:
+
+- 오픈 소스의 모범 사례에 대한 통찰력을 얻습니다.
+- 가장 인기 있는 딥러닝 라이브러리의 설계 원칙을 이해합니다.
+- 대규모 모델을 효율적으로 테스트하는 방법을 배웁니다.
+- `black`, `ruff`, `make fix-copies`와 같은 Python 유틸리티를 통합하여 깔끔하고 가독성 있는 코드를 작성하는 방법을 배웁니다.
+
+Hugging Face 팀은 항상 도움을 줄 준비가 되어 있으므로 혼자가 아니라는 점을 기억하세요. 🤗 ❤️
+
+시작에 앞서 🤗 Transformers에 원하는 모델을 추가하기 위해 [New model addition](https://github.com/huggingface/transformers/issues/new?assignees=&labels=New+model&template=new-model-addition.yml) 이슈를 열어야 합니다. 특정 모델을 기여하는 데 특별히 까다로운 기준을 가지지 않는 경우 [New model label](https://github.com/huggingface/transformers/labels/New%20model)을 필터링하여 요청되지 않은 모델이 있는지 확인하고 작업할 수 있습니다.
+
+새로운 모델 요청을 열었다면 첫 번째 단계는 🤗 Transformers에 익숙해지는 것입니다!
+
+## 🤗 Transformers의 전반적인 개요 [[general-overview-of-transformers]]
+
+먼저 🤗 Transformers에 대한 전반적인 개요를 파악해야 합니다. 🤗 Transformers는 매우 주관적인 라이브러리이기 때문에 해당 라이브러리의 철학이나 설계 선택 사항에 동의하지 않을 수도 있습니다. 그러나 우리의 경험상 라이브러리의 기본적인 설계 선택과 철학은 🤗 Transformers의 규모를 효율적으로 확장하면서 유지 보수 비용을 합리적인 수준으로 유지하는 것입니다.
+
+[라이브러리의 철학에 대한 문서](philosophy)를 읽는 것이 라이브러리를 더 잘 이해하는 좋은 시작점입니다. 모든 모델에 적용하려는 몇 가지 작업 방식에 대한 선택 사항이 있습니다:
+
+- 일반적으로 추상화보다는 구성을 선호합니다.
+- 코드를 복제하는 것이 항상 나쁜 것은 아닙니다. 코드의 가독성이나 접근성을 크게 향상시킨다면 복제하는 것은 좋습니다.
+- 모델 파일은 가능한 한 독립적으로 유지되어야 합니다. 따라서 특정 모델의 코드를 읽을 때 해당 `modeling_....py` 파일만 확인하면 됩니다.
+
+우리는 라이브러리의 코드가 제품을 제공하는 수단뿐만 아니라 개선하고자 하는 제품이라고도 생각합니다. 따라서 모델을 추가할 때, 사용자는 모델을 사용할 사람뿐만 아니라 코드를 읽고 이해하고 필요한 경우 조정할 수 있는 모든 사람까지도 포함한다는 점을 기억해야 합니다.
+
+이를 염두에 두고 일반적인 라이브러리 설계에 대해 조금 더 자세히 알아보겠습니다.
+
+### 모델 개요 [[overview-of-models]]
+
+모델을 성공적으로 추가하려면 모델과 해당 구성인 [`PreTrainedModel`] 및 [`PretrainedConfig`] 간의 상호작용을 이해하는 것이 중요합니다. 예를 들어, 🤗 Transformers에 추가하려는 모델을 `BrandNewBert`라고 부르겠습니다.
+
+다음을 살펴보겠습니다:
+
+
+
+Windows를 사용하는 경우 `RUN_SLOW=1`을 `SET RUN_SLOW=1`로 바꿔야 합니다.
+
+
+
+둘째로, *brand_new_bert*에 특화된 모든 기능도 별도의 테스트에서 추가로 테스트해야 합니다. 이 부분은 종종 잊히는데, 두 가지 측면에서 굉장히 유용합니다.
+
+- *brand_new_bert*의 특수 기능이 어떻게 작동해야 하는지 보여줌으로써 커뮤니티에게 모델 추가 과정에서 습득한 지식을 전달하는 데 도움이 됩니다.
+- 향후 기여자는 이러한 특수 테스트를 실행하여 모델에 대한 변경 사항을 빠르게 테스트할 수 있습니다.
+
+
+**9. 토크나이저 구현하기**
+
+다음으로, *brand_new_bert*의 토크나이저를 추가해야 합니다. 보통 토크나이저는 🤗 Transformers의 기존 토크나이저와 동일하거나 매우 유사합니다.
+
+토크나이저가 올바르게 작동하는지 확인하기 위해 먼저 원본 리포지토리에서 문자열을 입력하고 `input_ids`를 반환하는 스크립트를 생성하는 것이 좋습니다. 다음과 같은 유사한 스크립트일 수 있습니다 (의사 코드로 작성):
+
+```python
+input_str = "This is a long example input string containing special characters .$?-, numbers 2872 234 12 and words."
+model = BrandNewBertModel.load_pretrained_checkpoint("/path/to/checkpoint/")
+input_ids = model.tokenize(input_str)
+```
+
+원본 리포지토리를 자세히 살펴보고 올바른 토크나이저 함수를 찾거나, 복제본에서 변경 사항을 적용하여 `input_ids`만 출력하도록 해야 합니다. 원본 리포지토리를 사용하는 기능적인 토큰화 스크립트를 작성한 후, 🤗 Transformers의 유사한 스크립트를 생성해야 합니다. 다음과 같이 작성되어야 합니다:
+
+```python
+from transformers import BrandNewBertTokenizer
+
+input_str = "This is a long example input string containing special characters .$?-, numbers 2872 234 12 and words."
+
+tokenizer = BrandNewBertTokenizer.from_pretrained("/path/to/tokenizer/folder/")
+
+input_ids = tokenizer(input_str).input_ids
+```
+
+두 개의 `input_ids`가 동일한 값을 반환할 때, 마지막 단계로 토크나이저 테스트 파일도 추가해야 합니다.
+
+*brand_new_bert*의 모델링 테스트 파일과 유사하게, *brand_new_bert*의 토크나이제이션 테스트 파일에는 몇 가지 하드코딩된 통합 테스트가 포함되어야 합니다.
+
+**10. 종단 간 통합 테스트 실행**
+
+토크나이저를 추가한 후에는 모델과 토크나이저를 사용하여 몇 가지 종단 간 통합 테스트를 추가해야 합니다. `tests/models/brand_new_bert/test_modeling_brand_new_bert.py`에 추가해주세요. 이러한 테스트는 🤗 Transformers 구현이 예상대로 작동하는지를 의미 있는 text-to-text 예시로 보여줘야 합니다. 그 예시로는 *예를 들어* source-to-target 번역 쌍, article-to-summary 쌍, question-to-answer 쌍 등이 포함될 수 있습니다. 불러온 체크포인트 중 어느 것도 다운스트림 작업에서 미세 조정되지 않았다면, 모델 테스트만으로 충분합니다. 모델이 완전히 기능을 갖추었는지 확인하기 위해 마지막 단계로 GPU에서 모든 테스트를 실행하는 것이 좋습니다. 모델의 내부 텐서의 일부에 `.to(self.device)` 문을 추가하는 것을 잊었을 수 있으며, 이 경우 테스트에서 오류로 표시됩니다. GPU에 액세스할 수 없는 경우, Hugging Face 팀이 테스트를 대신 실행할 수 있습니다.
+
+**11. 기술문서 추가**
+
+이제 *brand_new_bert*에 필요한 모든 기능이 추가되었습니다. 거의 끝났습니다! 추가해야 할 것은 멋진 기술문서과 기술문서 페이지입니다. Cookiecutter가 `docs/source/model_doc/brand_new_bert.md`라는 템플릿 파일을 추가해줬을 것입니다. 이 페이지를 사용하기 전에 모델을 사용하는 사용자들은 일반적으로 이 페이지를 먼저 확인합니다. 따라서 문서는 이해하기 쉽고 간결해야 합니다. 모델을 사용하는 방법을 보여주기 위해 *팁*을 추가하는 것이 커뮤니티에 매우 유용합니다. 독스트링에 관련하여 Hugging Face 팀에 문의하는 것을 주저하지 마세요.
+
+다음으로, `src/transformers/models/brand_new_bert/modeling_brand_new_bert.py`에 추가된 독스트링이 올바르며 필요한 모든 입력 및 출력을 포함하도록 확인하세요. [여기](writing-documentation)에서 우리의 문서 작성 가이드와 독스트링 형식에 대한 상세 가이드가 있습니다. 문서는 일반적으로 커뮤니티와 모델의 첫 번째 접점이기 때문에, 문서는 적어도 코드만큼의 주의를 기울여야 합니다.
+
+**코드 리팩토링**
+
+좋아요, 이제 *brand_new_bert*를 위한 모든 필요한 코드를 추가했습니다. 이 시점에서 다음을 실행하여 잠재적으로 잘못된 코드 스타일을 수정해야 합니다:
+
+그리고 코딩 스타일이 품질 점검을 통과하는지 확인하기 위해 다음을 실행하고 확인해야 합니다:
+
+```bash
+make style
+```
+
+🤗 Transformers에는 여전히 실패할 수 있는 몇 가지 매우 엄격한 디자인 테스트가 있습니다. 이는 독스트링에 누락된 정보나 잘못된 명명 때문에 종종 발생합니다. 여기서 막히면 Hugging Face 팀이 도움을 줄 것입니다.
+
+```bash
+make quality
+```
+
+마지막으로, 코드가 정확히 작동하는 것을 확인한 후에는 항상 코드를 리팩토링하는 것이 좋은 생각입니다. 모든 테스트가 통과된 지금은 추가한 코드를 다시 검토하고 리팩토링하는 좋은 시기입니다.
+
+이제 코딩 부분을 완료했습니다. 축하합니다! 🎉 멋져요! 😎
+
+**12. 모델을 모델 허브에 업로드하세요**
+
+이 마지막 파트에서는 모든 체크포인트를 변환하여 모델 허브에 업로드하고 각 업로드된 모델 체크포인트에 대한 모델 카드를 추가해야 합니다. [Model sharing and uploading Page](model_sharing)를 읽고 허브 기능에 익숙해지세요. *brand_new_bert*의 저자 조직 아래에 모델을 업로드할 수 있는 필요한 액세스 권한을 얻기 위해 Hugging Face 팀과 협업해야 합니다. `transformers`의 모든 모델에 있는 `push_to_hub` 메서드는 체크포인트를 허브에 빠르고 효율적으로 업로드하는 방법입니다. 아래에 작은 코드 조각이 붙여져 있습니다:
+
+각 체크포인트에 적합한 모델 카드를 만드는 데 시간을 할애하는 것은 가치가 있습니다. 모델 카드는 체크포인트의 특성을 강조해야 합니다. *예를 들어* 이 체크포인트는 어떤 데이터셋에서 사전 훈련/세부 훈련되었는지? 이 모델은 어떤 하위 작업에서 사용해야 하는지? 그리고 모델을 올바르게 사용하는 방법에 대한 몇 가지 코드도 포함해야 합니다.
+
+```python
+brand_new_bert.push_to_hub("brand_new_bert")
+# Uncomment the following line to push to an organization.
+# brand_new_bert.push_to_hub("/brand_new_bert")
+```
+
+**13. (선택 사항) 노트북 추가**
+
+*brand_new_bert*를 다운스트림 작업에서 추론 또는 미세 조정에 사용하는 방법을 자세히 보여주는 노트북을 추가하는 것이 매우 유용합니다. 이것은 PR을 병합하는 데 필수적이지는 않지만 커뮤니티에 매우 유용합니다.
+
+**14. 완료된 PR 제출**
+
+이제 프로그래밍을 마쳤으며, 마지막 단계로 PR을 메인 브랜치에 병합해야 합니다. 보통 Hugging Face 팀은 이미 여기까지 도움을 주었을 것입니다. 그러나 PR에 멋진 설명을 추가하고 리뷰어에게 특정 디자인 선택 사항을 강조하려면 완료된 PR에 약간의 설명을 추가하는 시간을 할애하는 것이 가치가 있습니다.
+
+### 작업물을 공유하세요!! [[share-your-work]]
+
+이제 커뮤니티에서 작업물을 인정받을 시간입니다! 모델 추가 작업을 완료하는 것은 Transformers와 전체 NLP 커뮤니티에 큰 기여입니다. 당신의 코드와 이식된 사전 훈련된 모델은 수백, 심지어 수천 명의 개발자와 연구원에 의해 확실히 사용될 것입니다. 당신의 작업에 자랑스러워해야 하며 이를 커뮤니티와 공유해야 합니다.
+
+**당신은 커뮤니티 내 모든 사람들에게 매우 쉽게 접근 가능한 또 다른 모델을 만들었습니다! 🤯**
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/add_new_pipeline.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/add_new_pipeline.md
new file mode 100644
index 0000000000000000000000000000000000000000..42c9b57c9d7be675010069bc1803233befba410a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/add_new_pipeline.md
@@ -0,0 +1,244 @@
+
+
+# 어떻게 사용자 정의 파이프라인을 생성하나요? [[how-to-create-a-custom-pipeline]]
+
+이 가이드에서는 사용자 정의 파이프라인을 어떻게 생성하고 [허브](https://hf.co/models)에 공유하거나 🤗 Transformers 라이브러리에 추가하는 방법을 살펴보겠습니다.
+
+먼저 파이프라인이 수용할 수 있는 원시 입력을 결정해야 합니다.
+문자열, 원시 바이트, 딕셔너리 또는 가장 원하는 입력일 가능성이 높은 것이면 무엇이든 가능합니다.
+이 입력을 가능한 한 순수한 Python 형식으로 유지해야 (JSON을 통해 다른 언어와도) 호환성이 좋아집니다.
+이것이 전처리(`preprocess`) 파이프라인의 입력(`inputs`)이 될 것입니다.
+
+그런 다음 `outputs`를 정의하세요.
+`inputs`와 같은 정책을 따르고, 간단할수록 좋습니다.
+이것이 후처리(`postprocess`) 메소드의 출력이 될 것입니다.
+
+먼저 4개의 메소드(`preprocess`, `_forward`, `postprocess` 및 `_sanitize_parameters`)를 구현하기 위해 기본 클래스 `Pipeline`을 상속하여 시작합니다.
+
+
+```python
+from transformers import Pipeline
+
+
+class MyPipeline(Pipeline):
+ def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "maybe_arg" in kwargs:
+ preprocess_kwargs["maybe_arg"] = kwargs["maybe_arg"]
+ return preprocess_kwargs, {}, {}
+
+ def preprocess(self, inputs, maybe_arg=2):
+ model_input = Tensor(inputs["input_ids"])
+ return {"model_input": model_input}
+
+ def _forward(self, model_inputs):
+ # model_inputs == {"model_input": model_input}
+ outputs = self.model(**model_inputs)
+ # Maybe {"logits": Tensor(...)}
+ return outputs
+
+ def postprocess(self, model_outputs):
+ best_class = model_outputs["logits"].softmax(-1)
+ return best_class
+```
+
+이 분할 구조는 CPU/GPU에 대한 비교적 원활한 지원을 제공하는 동시에, 다른 스레드에서 CPU에 대한 사전/사후 처리를 수행할 수 있게 지원하는 것입니다.
+
+`preprocess`는 원래 정의된 입력을 가져와 모델에 공급할 수 있는 형식으로 변환합니다.
+더 많은 정보를 포함할 수 있으며 일반적으로 `Dict` 형태입니다.
+
+`_forward`는 구현 세부 사항이며 직접 호출할 수 없습니다.
+`forward`는 예상 장치에서 모든 것이 작동하는지 확인하기 위한 안전장치가 포함되어 있어 선호되는 호출 메소드입니다.
+실제 모델과 관련된 것은 `_forward` 메소드에 속하며, 나머지는 전처리/후처리 과정에 있습니다.
+
+`postprocess` 메소드는 `_forward`의 출력을 가져와 이전에 결정한 최종 출력 형식으로 변환합니다.
+
+`_sanitize_parameters`는 초기화 시간에 `pipeline(...., maybe_arg=4)`이나 호출 시간에 `pipe = pipeline(...); output = pipe(...., maybe_arg=4)`과 같이, 사용자가 원하는 경우 언제든지 매개변수를 전달할 수 있도록 허용합니다.
+
+`_sanitize_parameters`의 반환 값은 `preprocess`, `_forward`, `postprocess`에 직접 전달되는 3개의 kwargs 딕셔너리입니다.
+호출자가 추가 매개변수로 호출하지 않았다면 아무것도 채우지 마십시오.
+이렇게 하면 항상 더 "자연스러운" 함수 정의의 기본 인수를 유지할 수 있습니다.
+
+분류 작업에서 `top_k` 매개변수가 대표적인 예입니다.
+
+```python
+>>> pipe = pipeline("my-new-task")
+>>> pipe("This is a test")
+[{"label": "1-star", "score": 0.8}, {"label": "2-star", "score": 0.1}, {"label": "3-star", "score": 0.05}
+{"label": "4-star", "score": 0.025}, {"label": "5-star", "score": 0.025}]
+
+>>> pipe("This is a test", top_k=2)
+[{"label": "1-star", "score": 0.8}, {"label": "2-star", "score": 0.1}]
+```
+
+이를 달성하기 위해 우리는 `postprocess` 메소드를 기본 매개변수인 `5`로 업데이트하고 `_sanitize_parameters`를 수정하여 이 새 매개변수를 허용합니다.
+
+
+```python
+def postprocess(self, model_outputs, top_k=5):
+ best_class = model_outputs["logits"].softmax(-1)
+ # top_k를 처리하는 로직 추가
+ return best_class
+
+
+def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "maybe_arg" in kwargs:
+ preprocess_kwargs["maybe_arg"] = kwargs["maybe_arg"]
+
+ postprocess_kwargs = {}
+ if "top_k" in kwargs:
+ postprocess_kwargs["top_k"] = kwargs["top_k"]
+ return preprocess_kwargs, {}, postprocess_kwargs
+```
+
+입/출력을 가능한 한 간단하고 완전히 JSON 직렬화 가능한 형식으로 유지하려고 노력하십시오.
+이렇게 하면 사용자가 새로운 종류의 개체를 이해하지 않고도 파이프라인을 쉽게 사용할 수 있습니다.
+또한 사용 용이성을 위해 여러 가지 유형의 인수(오디오 파일은 파일 이름, URL 또는 순수한 바이트일 수 있음)를 지원하는 것이 비교적 일반적입니다.
+
+
+
+## 지원되는 작업 목록에 추가하기 [[adding-it-to-the-list-of-supported-tasks]]
+
+`new-task`를 지원되는 작업 목록에 등록하려면 `PIPELINE_REGISTRY`에 추가해야 합니다:
+
+```python
+from transformers.pipelines import PIPELINE_REGISTRY
+
+PIPELINE_REGISTRY.register_pipeline(
+ "new-task",
+ pipeline_class=MyPipeline,
+ pt_model=AutoModelForSequenceClassification,
+)
+```
+
+원하는 경우 기본 모델을 지정할 수 있으며, 이 경우 특정 개정(분기 이름 또는 커밋 해시일 수 있음, 여기서는 "abcdef")과 타입을 함께 가져와야 합니다:
+
+```python
+PIPELINE_REGISTRY.register_pipeline(
+ "new-task",
+ pipeline_class=MyPipeline,
+ pt_model=AutoModelForSequenceClassification,
+ default={"pt": ("user/awesome_model", "abcdef")},
+ type="text", # 현재 지원 유형: text, audio, image, multimodal
+)
+```
+
+## Hub에 파이프라인 공유하기 [[share-your-pipeline-on-the-hub]]
+
+Hub에 사용자 정의 파이프라인을 공유하려면 `Pipeline` 하위 클래스의 사용자 정의 코드를 Python 파일에 저장하기만 하면 됩니다.
+예를 들어, 다음과 같이 문장 쌍 분류를 위한 사용자 정의 파이프라인을 사용한다고 가정해 보겠습니다:
+
+```py
+import numpy as np
+
+from transformers import Pipeline
+
+
+def softmax(outputs):
+ maxes = np.max(outputs, axis=-1, keepdims=True)
+ shifted_exp = np.exp(outputs - maxes)
+ return shifted_exp / shifted_exp.sum(axis=-1, keepdims=True)
+
+
+class PairClassificationPipeline(Pipeline):
+ def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "second_text" in kwargs:
+ preprocess_kwargs["second_text"] = kwargs["second_text"]
+ return preprocess_kwargs, {}, {}
+
+ def preprocess(self, text, second_text=None):
+ return self.tokenizer(text, text_pair=second_text, return_tensors=self.framework)
+
+ def _forward(self, model_inputs):
+ return self.model(**model_inputs)
+
+ def postprocess(self, model_outputs):
+ logits = model_outputs.logits[0].numpy()
+ probabilities = softmax(logits)
+
+ best_class = np.argmax(probabilities)
+ label = self.model.config.id2label[best_class]
+ score = probabilities[best_class].item()
+ logits = logits.tolist()
+ return {"label": label, "score": score, "logits": logits}
+```
+
+구현은 프레임워크에 구애받지 않으며, PyTorch와 TensorFlow 모델에 대해 작동합니다.
+이를 `pair_classification.py`라는 파일에 저장한 경우, 다음과 같이 가져오고 등록할 수 있습니다:
+
+```py
+from pair_classification import PairClassificationPipeline
+from transformers.pipelines import PIPELINE_REGISTRY
+from transformers import AutoModelForSequenceClassification, TFAutoModelForSequenceClassification
+
+PIPELINE_REGISTRY.register_pipeline(
+ "pair-classification",
+ pipeline_class=PairClassificationPipeline,
+ pt_model=AutoModelForSequenceClassification,
+ tf_model=TFAutoModelForSequenceClassification,
+)
+```
+
+이 작업이 완료되면 사전훈련된 모델과 함께 사용할 수 있습니다.
+예를 들어, `sgugger/finetuned-bert-mrpc`은 MRPC 데이터 세트에서 미세 조정되어 문장 쌍을 패러프레이즈인지 아닌지를 분류합니다.
+
+```py
+from transformers import pipeline
+
+classifier = pipeline("pair-classification", model="sgugger/finetuned-bert-mrpc")
+```
+
+그런 다음 `push_to_hub` 메소드를 사용하여 허브에 공유할 수 있습니다:
+
+```py
+classifier.push_to_hub("test-dynamic-pipeline")
+```
+
+이렇게 하면 "test-dynamic-pipeline" 폴더 내에 `PairClassificationPipeline`을 정의한 파일이 복사되며, 파이프라인의 모델과 토크나이저도 저장한 후, `{your_username}/test-dynamic-pipeline` 저장소에 있는 모든 것을 푸시합니다.
+이후에는 `trust_remote_code=True` 옵션만 제공하면 누구나 사용할 수 있습니다.
+
+```py
+from transformers import pipeline
+
+classifier = pipeline(model="{your_username}/test-dynamic-pipeline", trust_remote_code=True)
+```
+
+## 🤗 Transformers에 파이프라인 추가하기 [[add-the-pipeline-to-transformers]]
+
+🤗 Transformers에 사용자 정의 파이프라인을 기여하려면, `pipelines` 하위 모듈에 사용자 정의 파이프라인 코드와 함께 새 모듈을 추가한 다음, `pipelines/__init__.py`에서 정의된 작업 목록에 추가해야 합니다.
+
+그런 다음 테스트를 추가해야 합니다.
+`tests/test_pipelines_MY_PIPELINE.py`라는 새 파일을 만들고 다른 테스트와 예제를 함께 작성합니다.
+
+`run_pipeline_test` 함수는 매우 일반적이며, `model_mapping` 및 `tf_model_mapping`에서 정의된 가능한 모든 아키텍처의 작은 무작위 모델에서 실행됩니다.
+
+이는 향후 호환성을 테스트하는 데 매우 중요하며, 누군가 `XXXForQuestionAnswering`을 위한 새 모델을 추가하면 파이프라인 테스트가 해당 모델에서 실행을 시도한다는 의미입니다.
+모델이 무작위이기 때문에 실제 값을 확인하는 것은 불가능하므로, 단순히 파이프라인 출력 `TYPE`과 일치시키기 위한 도우미 `ANY`가 있습니다.
+
+또한 2개(이상적으로는 4개)의 테스트를 구현해야 합니다.
+
+- `test_small_model_pt`: 이 파이프라인에 대한 작은 모델 1개를 정의(결과가 의미 없어도 상관없음)하고 파이프라인 출력을 테스트합니다.
+결과는 `test_small_model_tf`와 동일해야 합니다.
+- `test_small_model_tf`: 이 파이프라인에 대한 작은 모델 1개를 정의(결과가 의미 없어도 상관없음)하고 파이프라인 출력을 테스트합니다.
+결과는 `test_small_model_pt`와 동일해야 합니다.
+- `test_large_model_pt`(`선택사항`): 결과가 의미 있을 것으로 예상되는 실제 파이프라인에서 파이프라인을 테스트합니다.
+이러한 테스트는 속도가 느리므로 이를 표시해야 합니다.
+여기서의 목표는 파이프라인을 보여주고 향후 릴리즈에서의 변화가 없는지 확인하는 것입니다.
+- `test_large_model_tf`(`선택사항`): 결과가 의미 있을 것으로 예상되는 실제 파이프라인에서 파이프라인을 테스트합니다.
+이러한 테스트는 속도가 느리므로 이를 표시해야 합니다.
+여기서의 목표는 파이프라인을 보여주고 향후 릴리즈에서의 변화가 없는지 확인하는 것입니다.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/attention.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/attention.md
new file mode 100644
index 0000000000000000000000000000000000000000..d9a5eeee1b73eada3d0d704b2ff6744f545c6d2b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/attention.md
@@ -0,0 +1,54 @@
+
+
+# 어텐션 메커니즘[[attention_mechanisms]]
+
+대부분의 트랜스포머 모델은 정방행렬인 전체 어텐션을 사용합니다.
+하지만 이는 긴 텍스트를 다룰 때는 큰 계산 병목 현상을 유발할 수 있습니다.
+`Longformer`와 `Reformer`는 훈련 속도를 높이기 위해 어텐션 행렬의 희소 버전을 사용하여 효율을 높이려는 모델입니다.
+
+## LSH 어텐션[[lsh_attention]]
+
+
+[Reformer](model_doc/reformer)는 LSH(Locality Sensitive Hashing) 어텐션을 사용합니다. softmax(QK^t)에서는 행렬 QK^t의 (softmax 차원에서) 가장 큰 요소들만 유용한 기여를 할 것입니다.
+따라서 각각의 쿼리 q에 대해, q와 가까운 키 k만 고려할 수 있습니다. 해시 함수는 q와 k가 가까운지 여부를 결정하는 데 사용됩니다.
+어텐션 마스크는 현재 토큰을 마스킹하여 변경됩니다. 이 때 첫 번째 위치의 토큰은 제외합니다. 왜냐하면 쿼리와 키가 동일한 값을 갖게 되기 때문입니다(서로 매우 유사함).
+해시는 약간의 무작위성을 가질 수 있으므로, 실제로는 여러 개의 해시 함수가 사용되고 (`n_rounds` 매개변수에 의해 결정됨) 그 후에 평균값을 취하게 됩니다.
+
+## 지역 어텐션[[local_attention]]
+
+[Longformer](model_doc/longformer)는 지역 어텐션을 사용합니다. 종종 특정 토큰에 대해 지역 컨텍스트(예: 왼쪽과 오른쪽에 있는 두 개의 토큰은 무엇인가요?)만으로도 작업을 수행하는데 충분합니다.
+또한 작은 창(window)을 가진 어텐션 레이어를 쌓음으로써 마지막 레이어는 창 내의 토큰뿐만 아니라 더 많은 수의 토큰에 대한 수용 영역(receptive field)을 갖게 되어 전체 문장의 표현을 구축할 수 있습니다.
+
+사전에 선택된 일부 입력 토큰들은 전역 어텐션을 받습니다. 이 몇 개의 토큰에 대해서는 어텐션 행렬이 모든 토큰에 접근할 수 있으며, 이 과정은 대칭적으로 이루어집니다.
+다른 모든 토큰들은 로컬 창 내의 토큰들에 더해 해당 특정 토큰들에도 접근할 수 있습니다. 이는 논문의 Figure 2d에서 나타나며, 아래에 샘플 어텐션 마스크가 제시되어 있습니다:
+
+
+
+
+
+
+아키텍처는 모델의 골격을 의미하며 체크포인트는 주어진 아키텍처에 대한 가중치입니다. 예를 들어, [BERT](https://huggingface.co/google-bert/bert-base-uncased)는 아키텍처이고, `google-bert/bert-base-uncased`는 체크포인트입니다. 모델은 아키텍처 또는 체크포인트를 의미할 수 있는 일반적인 용어입니다.
+
+
+
+이 튜토리얼에서는 다음을 학습합니다:
+
+* 사전 학습된 토크나이저 로드하기.
+* 사전 학습된 이미지 프로세서 로드하기.
+* 사전 학습된 특징 추출기 로드하기.
+* 사전 훈련된 프로세서 로드하기.
+* 사전 학습된 모델 로드하기.
+
+## AutoTokenizer[[autotokenizer]]
+
+거의 모든 NLP 작업은 토크나이저로 시작됩니다. 토크나이저는 사용자의 입력을 모델에서 처리할 수 있는 형식으로 변환합니다.
+[`AutoTokenizer.from_pretrained`]로 토크나이저를 로드합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+```
+
+그리고 아래와 같이 입력을 토큰화합니다:
+
+```py
+>>> sequence = "In a hole in the ground there lived a hobbit."
+>>> print(tokenizer(sequence))
+{'input_ids': [101, 1999, 1037, 4920, 1999, 1996, 2598, 2045, 2973, 1037, 7570, 10322, 4183, 1012, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+## AutoImageProcessor[[autoimageprocessor]]
+
+비전 작업의 경우 이미지 프로세서가 이미지를 올바른 입력 형식으로 처리합니다.
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+```
+
+
+## AutoFeatureExtractor[[autofeatureextractor]]
+
+오디오 작업의 경우 특징 추출기가 오디오 신호를 올바른 입력 형식으로 처리합니다.
+
+[`AutoFeatureExtractor.from_pretrained`]로 특징 추출기를 로드합니다:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained(
+... "ehcalabres/wav2vec2-lg-xlsr-en-speech-emotion-recognition"
+... )
+```
+
+## AutoProcessor[[autoprocessor]]
+
+멀티모달 작업에는 두 가지 유형의 전처리 도구를 결합한 프로세서가 필요합니다. 예를 들어 LayoutLMV2 모델에는 이미지를 처리하는 이미지 프로세서와 텍스트를 처리하는 토크나이저가 필요하며, 프로세서는 이 두 가지를 결합합니다.
+
+[`AutoProcessor.from_pretrained()`]로 프로세서를 로드합니다:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("microsoft/layoutlmv2-base-uncased")
+```
+
+## AutoModel[[automodel]]
+
+
+
+마지막으로 AutoModelFor클래스를 사용하면 주어진 작업에 대해 미리 학습된 모델을 로드할 수 있습니다 (사용 가능한 작업의 전체 목록은 [여기](model_doc/auto)를 참조하세요). 예를 들어, [`AutoModelForSequenceClassification.from_pretrained`]를 사용하여 시퀀스 분류용 모델을 로드할 수 있습니다:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+동일한 체크포인트를 쉽게 재사용하여 다른 작업에 아키텍처를 로드할 수 있습니다:
+
+```py
+>>> from transformers import AutoModelForTokenClassification
+
+>>> model = AutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+PyTorch모델의 경우 `from_pretrained()` 메서드는 내부적으로 피클을 사용하여 안전하지 않은 것으로 알려진 `torch.load()`를 사용합니다.
+일반적으로 신뢰할 수 없는 소스에서 가져왔거나 변조되었을 수 있는 모델은 로드하지 마세요. 허깅 페이스 허브에서 호스팅되는 공개 모델의 경우 이러한 보안 위험이 부분적으로 완화되며, 각 커밋 시 멀웨어를 [검사합니다](https://huggingface.co/docs/hub/security-malware). GPG를 사용해 서명된 [커밋 검증](https://huggingface.co/docs/hub/security-gpg#signing-commits-with-gpg)과 같은 모범사례는 [문서](https://huggingface.co/docs/hub/security)를 참조하세요.
+
+텐서플로우와 Flax 체크포인트는 영향을 받지 않으며, `from_pretrained`메서드에 `from_tf` 와 `from_flax` 키워드 가변 인자를 사용하여 이 문제를 우회할 수 있습니다.
+
+
+
+일반적으로 AutoTokenizer 클래스와 AutoModelFor 클래스를 사용하여 미리 학습된 모델 인스턴스를 로드하는 것이 좋습니다. 이렇게 하면 매번 올바른 아키텍처를 로드할 수 있습니다. 다음 [튜토리얼](preprocessing)에서는 새롭게 로드한 토크나이저, 이미지 프로세서, 특징 추출기를 사용하여 미세 튜닝용 데이터 세트를 전처리하는 방법에 대해 알아봅니다.
+
+
+마지막으로 `TFAutoModelFor` 클래스를 사용하면 주어진 작업에 대해 사전 훈련된 모델을 로드할 수 있습니다. (사용 가능한 작업의 전체 목록은 [여기](model_doc/auto)를 참조하세요. 예를 들어, [`TFAutoModelForSequenceClassification.from_pretrained`]로 시퀀스 분류를 위한 모델을 로드합니다:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+쉽게 동일한 체크포인트를 재사용하여 다른 작업에 아키텍처를 로드할 수 있습니다:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+일반적으로, `AutoTokenizer`클래스와 `TFAutoModelFor` 클래스를 사용하여 미리 학습된 모델 인스턴스를 로드하는 것이 좋습니다. 이렇게 하면 매번 올바른 아키텍처를 로드할 수 있습니다. 다음 [튜토리얼](preprocessing)에서는 새롭게 로드한 토크나이저, 이미지 프로세서, 특징 추출기를 사용하여 미세 튜닝용 데이터 세트를 전처리하는 방법에 대해 알아봅니다.
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/bertology.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/bertology.md
new file mode 100644
index 0000000000000000000000000000000000000000..7b4f3dc4c4939bb44c401f96bf69f53cd179e5bd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/bertology.md
@@ -0,0 +1,41 @@
+
+
+# BERTology
+
+BERT와 같은 대규모 트랜스포머의 내부 동작을 조사하는 연구 분야가 점점 더 중요해지고 있습니다.
+혹자는 "BERTology"라 칭하기도 합니다. 이 분야의 좋은 예시는 다음과 같습니다:
+
+
+- BERT는 고전적인 NLP 파이프라인의 재발견 - Ian Tenney, Dipanjan Das, Ellie Pavlick:
+ https://arxiv.org/abs/1905.05950
+- 16개의 헤드가 정말로 1개보다 나은가? - Paul Michel, Omer Levy, Graham Neubig:
+ https://arxiv.org/abs/1905.10650
+- BERT는 무엇을 보는가? BERT의 어텐션 분석 - Kevin Clark, Urvashi Khandelwal, Omer Levy, Christopher D. Manning:
+ https://arxiv.org/abs/1906.04341
+- CAT-probing: 프로그래밍 언어에 대해 사전훈련된 모델이 어떻게 코드 구조를 보는지 알아보기 위한 메트릭 기반 접근 방법:
+ https://arxiv.org/abs/2210.04633
+
+우리는 이 새로운 연구 분야의 발전을 돕기 위해, BERT/GPT/GPT-2 모델에 내부 표현을 살펴볼 수 있는 몇 가지 기능을 추가했습니다.
+이 기능들은 주로 Paul Michel의 훌륭한 작업을 참고하여 개발되었습니다
+(https://arxiv.org/abs/1905.10650):
+
+
+- BERT/GPT/GPT-2의 모든 은닉 상태에 접근하기,
+- BERT/GPT/GPT-2의 각 헤드의 모든 어텐션 가중치에 접근하기,
+- 헤드의 출력 값과 그래디언트를 검색하여 헤드 중요도 점수를 계산하고 https://arxiv.org/abs/1905.10650에서 설명된 대로 헤드를 제거하는 기능을 제공합니다.
+
+이러한 기능들을 이해하고 직접 사용해볼 수 있도록 [bertology.py](https://github.com/huggingface/transformers/tree/main/examples/research_projects/bertology/run_bertology.py) 예제 스크립트를 추가했습니다. 이 예제 스크립트에서는 GLUE에 대해 사전훈련된 모델에서 정보를 추출하고 모델을 가지치기(prune)해봅니다.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/big_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/big_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..3180b51117a97b93566775485455e157ee7bd6ff
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/big_models.md
@@ -0,0 +1,122 @@
+
+
+# 큰 모델 인스턴스화 [[instantiating-a-big-model]]
+
+매우 큰 사전훈련된 모델을 사용하려면, RAM 사용을 최소화해야 하는 과제가 있습니다. 일반적인 PyTorch 워크플로우는 다음과 같습니다:
+
+1. 무작위 가중치로 모델을 생성합니다.
+2. 사전훈련된 가중치를 불러옵니다.
+3. 사전훈련된 가중치를 무작위 모델에 적용합니다.
+
+1단계와 2단계 모두 모델의 전체 버전을 메모리에 적재해야 하며, 대부분 문제가 없지만 모델이 기가바이트급의 용량을 차지하기 시작하면 복사본 2개가 RAM을 초과하여 메모리 부족 이슈를 야기할 수 있습니다. 더 심각한 문제는 분산 학습을 위해 `torch.distributed`를 사용하는 경우, 프로세스마다 사전훈련된 모델을 로드하고 복사본을 2개씩 RAM에 저장한다는 것입니다.
+
+
+
+무작위로 생성된 모델은 "비어 있는" (즉 그때 메모리에 있던 것으로 이뤄진) 텐서로 초기화되며 메모리 공간을 차지합니다. 초기화된 모델/파라미터의 종류에 적합한 분포(예: 정규 분포)에 따른 무작위 초기화는 가능한 한 빠르게 하기 위해 초기화되지 않은 가중치에 대해 3단계 이후에만 수행됩니다!
+
+
+
+이 안내서에서는 Transformers가 이 문제를 해결하기 위해 제공하는 솔루션을 살펴봅니다. 주의할 점은 아직 활발히 개발 중인 분야이므로 여기서 설명하는 API가 앞으로 약간 변경될 수 있다는 것입니다.
+
+## 샤딩된 체크포인트 [[sharded-checkpoints]]
+
+4.18.0 버전 이후, 10GB 이상의 공간을 차지하는 모델 체크포인트는 자동으로 작은 조각들로 샤딩됩니다. `model.save_pretrained(save_dir)`를 실행할 때 하나의 단일 체크포인트를 가지게 될 대신, 여러 부분 체크포인트(각각의 크기는 10GB 미만)와 매개변수 이름을 해당 파일에 매핑하는 인덱스가 생성됩니다.
+
+`max_shard_size` 매개변수로 샤딩 전 최대 크기를 제어할 수 있으므로, 이 예제를 위해 샤드 크기가 작은 일반 크기의 모델을 사용하겠습니다: 전통적인 BERT 모델을 사용해 봅시다.
+
+```py
+from transformers import AutoModel
+
+model = AutoModel.from_pretrained("google-bert/bert-base-cased")
+```
+
+[`~PreTrainedModel.save_pretrained`]을 사용하여 모델을 저장하면, 모델의 구성과 가중치가 들어있는 두 개의 파일이 있는 새 폴더가 생성됩니다:
+
+```py
+>>> import os
+>>> import tempfile
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir)
+... print(sorted(os.listdir(tmp_dir)))
+['config.json', 'pytorch_model.bin']
+```
+
+이제 최대 샤드 크기를 200MB로 사용해 봅시다:
+
+```py
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... print(sorted(os.listdir(tmp_dir)))
+['config.json', 'pytorch_model-00001-of-00003.bin', 'pytorch_model-00002-of-00003.bin', 'pytorch_model-00003-of-00003.bin', 'pytorch_model.bin.index.json']
+```
+
+모델의 구성에 더해, 세 개의 다른 가중치 파일과 파라미터 이름과 해당 파일의 매핑이 포함된 `index.json` 파일을 볼 수 있습니다. 이러한 체크포인트는 [`~PreTrainedModel.from_pretrained`] 메서드를 사용하여 완전히 다시 로드할 수 있습니다:
+
+```py
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... new_model = AutoModel.from_pretrained(tmp_dir)
+```
+
+큰 모델의 경우 이러한 방식으로 처리하는 주된 장점은 위에서 보여준 흐름의 2단계에서, 각 샤드가 이전 샤드 다음에 로드되므로 메모리 사용량이 모델 크기와 가장 큰 샤드의 크기를 초과하지 않는다는 점입니다.
+
+이 인덱스 파일은 키가 체크포인트에 있는지, 그리고 해당 가중치가 어디에 저장되어 있는지를 결정하는 데 사용됩니다. 이 인덱스를 json과 같이 로드하고 딕셔너리를 얻을 수 있습니다:
+
+```py
+>>> import json
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... with open(os.path.join(tmp_dir, "pytorch_model.bin.index.json"), "r") as f:
+... index = json.load(f)
+
+>>> print(index.keys())
+dict_keys(['metadata', 'weight_map'])
+```
+
+메타데이터는 현재 모델의 총 크기만 포함됩니다. 앞으로 다른 정보를 추가할 계획입니다:
+
+```py
+>>> index["metadata"]
+{'total_size': 433245184}
+```
+
+가중치 맵은 이 인덱스의 주요 부분으로, 각 매개변수 이름(PyTorch 모델 `state_dict`에서 보통 찾을 수 있는)을 해당 파일에 매핑합니다:
+
+```py
+>>> index["weight_map"]
+{'embeddings.LayerNorm.bias': 'pytorch_model-00001-of-00003.bin',
+ 'embeddings.LayerNorm.weight': 'pytorch_model-00001-of-00003.bin',
+ ...
+```
+
+만약 [`~PreTrainedModel.from_pretrained`]를 사용하지 않고 모델 내에서 이러한 샤딩된 체크포인트를 직접 가져오려면 (전체 체크포인트를 위해 `model.load_state_dict()`를 수행하는 것처럼), [`~modeling_utils.load_sharded_checkpoint`]를 사용해야 합니다.
+
+```py
+>>> from transformers.modeling_utils import load_sharded_checkpoint
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... load_sharded_checkpoint(model, tmp_dir)
+```
+
+## 저(低)메모리 로딩 [[low-memory-loading]]
+
+샤딩된 체크포인트는 위에서 언급한 작업 흐름의 2단계에서 메모리 사용량을 줄이지만, 저(低)메모리 설정에서 모델을 사용하기 위해 우리의 Accelerate 라이브러리를 기반으로 한 도구를 활용하는 것이 좋습니다.
+
+자세한 사항은 다음 가이드를 참조해주세요: [Accelerate로 대규모 모델 가져오기 (영문)](../en/main_classes/model#large-model-loading)
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/chat_templating.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/chat_templating.md
new file mode 100644
index 0000000000000000000000000000000000000000..5e6cbc4491dd9951f42f00b8c5022e72dda920c6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/chat_templating.md
@@ -0,0 +1,720 @@
+
+
+# 채팅 모델을 위한 템플릿[[templates-for-chat-models]]
+
+## 소개[[introduction]]
+
+요즘 LLM의 가장 흔한 활용 사례 중 하나는 **채팅**입니다. 채팅은 일반적인 언어 모델처럼 단일 문자열을 이어가는 대신 여러 개의 **메시지**로 구성된 대화를 이어갑니다. 이 대화에는 "사용자"나 "어시스턴트"와 같은 **역할**과 메시지 텍스트가 포함됩니다.
+
+토큰화와 마찬가지로, 다양한 모델은 채팅에 대해 매우 다른 입력 형식을 기대합니다. 이것이 우리가 **채팅 템플릿**을 기능으로 추가한 이유입니다. 채팅 템플릿은 토크나이저의 일부입니다. 채팅 템플릿은 대화 목록을 모델이 기대하는 형식인 '단일 토큰화가 가능한 문자열'로 변환하는 방법을 지정합니다.
+
+`BlenderBot` 모델을 사용한 간단한 예제를 통해 이를 구체적으로 살펴보겠습니다. BlenderBot은 기본적으로 매우 간단한 템플릿을 가지고 있으며, 주로 대화 라운드 사이에 공백을 추가합니다:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/blenderbot-400M-distill")
+
+>>> chat = [
+... {"role": "user", "content": "Hello, how are you?"},
+... {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+... {"role": "user", "content": "I'd like to show off how chat templating works!"},
+... ]
+
+>>> tokenizer.apply_chat_template(chat, tokenize=False)
+" Hello, how are you? I'm doing great. How can I help you today? I'd like to show off how chat templating works!"
+```
+
+전체 채팅이 하나의 문자열로 압축된 것을 확인할 수 있습니다. 기본 설정인 `tokenize=True`를 사용하면, 그 문자열도 토큰화됩니다. 더 복잡한 템플릿을 사용하기 위해 `mistralai/Mistral-7B-Instruct-v0.1` 모델을 사용해 보겠습니다.
+
+```python
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-Instruct-v0.1")
+
+>>> chat = [
+... {"role": "user", "content": "Hello, how are you?"},
+... {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+... {"role": "user", "content": "I'd like to show off how chat templating works!"},
+... ]
+
+>>> tokenizer.apply_chat_template(chat, tokenize=False)
+"[INST] Hello, how are you? [/INST]I'm doing great. How can I help you today? [INST] I'd like to show off how chat templating works! [/INST]"
+```
+
+이번에는 토크나이저가 [INST]와 [/INST] 제어 토큰을 추가하여 사용자 메시지의 시작과 끝을 표시했습니다(어시스턴트 메시지 제외). Mistral-instruct는 이러한 토큰으로 훈련되었지만, BlenderBot은 그렇지 않았습니다.
+
+## 채팅 템플릿을 어떻게 사용하나요?[[how-do-i-use-chat-templates]]
+
+위의 예에서 볼 수 있듯이 채팅 템플릿은 사용하기 쉽습니다. `role`과 `content` 키가 포함된 메시지 목록을 작성한 다음, [`~PreTrainedTokenizer.apply_chat_template`] 메서드에 전달하기만 하면 됩니다. 이렇게 하면 바로 사용할 수 있는 출력이 생성됩니다! 모델 생성의 입력으로 채팅 템플릿을 사용할 때, `add_generation_prompt=True`를 사용하여 [생성 프롬프트](#what-are-generation-prompts)를 추가하는 것도 좋은 방법입니다.
+
+다음은 `Zephyr` 어시스턴트 모델을 사용하여 `model.generate()`의 입력을 준비하는 예제입니다:
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+checkpoint = "HuggingFaceH4/zephyr-7b-beta"
+tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+model = AutoModelForCausalLM.from_pretrained(checkpoint) # 여기서 bfloat16 사용 및/또는 GPU로 이동할 수 있습니다.
+
+
+messages = [
+ {
+ "role": "system",
+ "content": "You are a friendly chatbot who always responds in the style of a pirate",
+ },
+ {"role": "user", "content": "How many helicopters can a human eat in one sitting?"},
+ ]
+tokenized_chat = tokenizer.apply_chat_template(messages, tokenize=True, add_generation_prompt=True, return_tensors="pt")
+print(tokenizer.decode(tokenized_chat[0]))
+```
+이렇게 하면 Zephyr가 기대하는 입력 형식의 문자열이 생성됩니다.
+```text
+<|system|>
+You are a friendly chatbot who always responds in the style of a pirate
+<|user|>
+How many helicopters can a human eat in one sitting?
+<|assistant|>
+```
+
+이제 입력이 Zephyr에 맞게 형식이 지정되었으므로 모델을 사용하여 사용자의 질문에 대한 응답을 생성할 수 있습니다:
+
+```python
+outputs = model.generate(tokenized_chat, max_new_tokens=128)
+print(tokenizer.decode(outputs[0]))
+```
+
+이렇게 하면 다음과 같은 결과가 나옵니다:
+
+```text
+<|system|>
+You are a friendly chatbot who always responds in the style of a pirate
+<|user|>
+How many helicopters can a human eat in one sitting?
+<|assistant|>
+Matey, I'm afraid I must inform ye that humans cannot eat helicopters. Helicopters are not food, they are flying machines. Food is meant to be eaten, like a hearty plate o' grog, a savory bowl o' stew, or a delicious loaf o' bread. But helicopters, they be for transportin' and movin' around, not for eatin'. So, I'd say none, me hearties. None at all.
+```
+
+이제 쉬워졌죠!
+
+## 채팅을 위한 자동화된 파이프라인이 있나요?[[is-there-an-automated-pipeline-for-chat]]
+
+네, 있습니다! 우리의 텍스트 생성 파이프라인은 채팅 입력을 지원하여 채팅 모델을 쉽게 사용할 수 있습니다. 이전에는 "ConversationalPipeline" 클래스를 사용했지만, 이제는 이 기능이 [`TextGenerationPipeline`]에 통합되었습니다. 이번에는 파이프라인을 사용하여 `Zephyr` 예제를 다시 시도해 보겠습니다:
+
+```python
+from transformers import pipeline
+
+pipe = pipeline("text-generation", "HuggingFaceH4/zephyr-7b-beta")
+messages = [
+ {
+ "role": "system",
+ "content": "You are a friendly chatbot who always responds in the style of a pirate",
+ },
+ {"role": "user", "content": "How many helicopters can a human eat in one sitting?"},
+]
+print(pipe(messages, max_new_tokens=128)[0]['generated_text'][-1]) # 어시스턴트의 응답을 출력합니다.
+```
+
+```text
+{'role': 'assistant', 'content': "Matey, I'm afraid I must inform ye that humans cannot eat helicopters. Helicopters are not food, they are flying machines. Food is meant to be eaten, like a hearty plate o' grog, a savory bowl o' stew, or a delicious loaf o' bread. But helicopters, they be for transportin' and movin' around, not for eatin'. So, I'd say none, me hearties. None at all."}
+```
+
+파이프라인은 토큰화와 `apply_chat_template` 호출 의 세부 사항을 모두 처리해주기 때문에, 모델에 채팅 템플릿이 있으면 파이프라인을 초기화하고 메시지 목록을 전달하기만 하면 됩니다!
+
+
+## "생성 프롬프트"란 무엇인가요?[[what-are-generation-prompts]]
+
+`apply_chat_template` 메서드에는 `add_generation_prompt` 인수가 있다는 것을 눈치챘을 것입니다. 이 인수는 템플릿에 봇 응답의 시작을 나타내는 토큰을 추가하도록 지시합니다. 예를 들어, 다음과 같은 채팅을 고려해 보세요:
+
+```python
+messages = [
+ {"role": "user", "content": "Hi there!"},
+ {"role": "assistant", "content": "Nice to meet you!"},
+ {"role": "user", "content": "Can I ask a question?"}
+]
+```
+
+Zephyr 예제에서 보았던 것과 같이, 생성 프롬프트 없이 ChatML 템플릿을 사용한다면 다음과 같이 보일 것입니다:
+
+```python
+tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=False)
+"""<|im_start|>user
+Hi there!<|im_end|>
+<|im_start|>assistant
+Nice to meet you!<|im_end|>
+<|im_start|>user
+Can I ask a question?<|im_end|>
+"""
+```
+
+생성 프롬프트가 **있는** 경우는 다음과 같습니다:
+
+```python
+tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+"""<|im_start|>user
+Hi there!<|im_end|>
+<|im_start|>assistant
+Nice to meet you!<|im_end|>
+<|im_start|>user
+Can I ask a question?<|im_end|>
+<|im_start|>assistant
+"""
+```
+
+이번에는 봇 응답의 시작을 나타내는 토큰을 추가한 것을 주목하세요. 이렇게 하면 모델이 텍스트를 생성할 때 사용자의 메시지를 계속하는 대신 봇 응답을 작성하게 됩니다. 기억하세요, 채팅 모델은 여전히 언어 모델일 뿐이며, 그들에게 채팅은 특별한 종류의 텍스트일 뿐입니다! 적절한 제어 토큰으로 안내해야 채팅 모델이 무엇을 해야 하는지 알 수 있습니다.
+
+모든 모델이 생성 프롬프트를 필요로 하는 것은 아닙니다. BlenderBot과 LLaMA 같은 일부 모델은 봇 응답 전에 특별한 토큰이 없습니다. 이러한 경우 `add_generation_prompt` 인수는 효과가 없습니다. `add_generation_prompt`의 정확한 효과는 사용 중인 템플릿에 따라 다릅니다.
+
+
+
+## 채팅 템플릿을 훈련에 사용할 수 있나요?[[can-i-use-chat-templates-in-training]]
+
+네! 이 방법은 채팅 템플릿을 모델이 훈련 중에 보는 토큰과 일치하도록 하는 좋은 방법입니다. 데이터 세트에 대한 전처리 단계로 채팅 템플릿을 적용하는 것이 좋습니다. 그 후에는 다른 언어 모델 훈련 작업과 같이 계속할 수 있습니다. 훈련할 때는 일반적으로 `add_generation_prompt=False`로 설정해야 합니다. 어시스턴트 응답을 프롬프트하는 추가 토큰은 훈련 중에는 도움이 되지 않기 때문입니다. 예제를 보겠습니다:
+
+```python
+from transformers import AutoTokenizer
+from datasets import Dataset
+
+tokenizer = AutoTokenizer.from_pretrained("HuggingFaceH4/zephyr-7b-beta")
+
+chat1 = [
+ {"role": "user", "content": "Which is bigger, the moon or the sun?"},
+ {"role": "assistant", "content": "The sun."}
+]
+chat2 = [
+ {"role": "user", "content": "Which is bigger, a virus or a bacterium?"},
+ {"role": "assistant", "content": "A bacterium."}
+]
+
+dataset = Dataset.from_dict({"chat": [chat1, chat2]})
+dataset = dataset.map(lambda x: {"formatted_chat": tokenizer.apply_chat_template(x["chat"], tokenize=False, add_generation_prompt=False)})
+print(dataset['formatted_chat'][0])
+```
+다음과 같은 결과를 얻을 수 있습니다:
+```text
+<|user|>
+Which is bigger, the moon or the sun?
+<|assistant|>
+The sun.
+```
+
+여기서부터는 일반적인 언어 모델 작업과 같이 `formatted_chat` 열을 사용하여 훈련을 계속하면 됩니다.
+
+
+`apply_chat_template(tokenize=False)`로 텍스트를 형식화한 다음 별도의 단계에서 토큰화하는 경우, `add_special_tokens=False` 인수를 설정해야 합니다. `apply_chat_template(tokenize=True)`를 사용하는 경우에는 이 문제를 걱정할 필요가 없습니다!
+기본적으로 일부 토크나이저는 토큰화할 때 `` 및 ``와 같은 특별 토큰을 추가합니다. 채팅 템플릿은 항상 필요한 모든 특별 토큰을 포함해야 하므로, 기본 `add_special_tokens=True`로 추가적인 특별 토큰을 추가하면 잘못되거나 중복되는 특별 토큰을 생성하여 모델 성능이 저하될 수 있습니다.
+
+
+## 고급: 채팅 템플릿에 추가 입력 사용[[advanced-extra-inputs-to-chat-templates]]
+
+`apply_chat_template`가 필요한 유일한 인수는 `messages`입니다. 그러나 `apply_chat_template`에 키워드 인수를 전달하면 템플릿 내부에서 사용할 수 있습니다. 이를 통해 채팅 템플릿을 다양한 용도로 사용할 수 있는 자유를 얻을 수 있습니다. 이러한 인수의 이름이나 형식에는 제한이 없어 문자열, 리스트, 딕셔너리 등을 전달할 수 있습니다.
+
+그렇긴 하지만, 이러한 추가 인수의 일반적인 사용 사례로 '함수 호출을 위한 도구'나 '검색 증강 생성을 위한 문서'를 전달하는 것이 있습니다. 이러한 일반적인 경우에 대해 인수의 이름과 형식에 대한 몇 가지 권장 사항이 있으며, 이는 아래 섹션에 설명되어 있습니다. 우리는 모델 작성자에게 도구 호출 코드를 모델 간에 쉽게 전송할 수 있도록 채팅 템플릿을 이 형식과 호환되도록 만들 것을 권장합니다.
+
+## 고급: 도구 사용 / 함수 호출[[advanced-tool-use--function-calling]]
+
+"도구 사용" LLM은 답변을 생성하기 전에 외부 도구로서 함수를 호출할 수 있습니다. 도구 사용 모델에 도구를 전달할 때는 단순히 함수 목록을 `tools` 인수로 전달할 수 있습니다:
+
+```python
+import datetime
+
+def current_time():
+ """현재 현지 시간을 문자열로 가져옵니다."""
+ return str(datetime.now())
+
+def multiply(a: float, b: float):
+ """
+ 두 숫자를 곱하는 함수
+
+ 인수:
+ a: 곱할 첫 번째 숫자
+ b: 곱할 두 번째 숫자
+ """
+ return a * b
+
+tools = [current_time, multiply]
+
+model_input = tokenizer.apply_chat_template(
+ messages,
+ tools=tools
+)
+```
+
+이것이 올바르게 작동하려면 함수를 위 형식으로 작성해야 도구로 올바르게 구문 분석할 수 있습니다. 구체적으로 다음 규칙을 따라야 합니다:
+
+- 함수는 설명적인 이름을 가져야 합니다.
+- 모든 인수에는 타입 힌트가 있어야 합니다.
+- 함수에는 표준 Google 스타일의 도크스트링이 있어야 합니다(즉, 초기 함수 설명 다음에 인수를 설명하는 `Args:` 블록이 있어야 합니다).
+- `Args:` 블록에는 타입을 포함하지 마세요. 즉, `a (int): The first number to multiply` 대신 `a: The first number to multiply`라고 작성해야 합니다. 타입 힌트는 함수 헤더에 있어야 합니다.
+- 함수에는 반환 타입과 도크스트링에 `Returns:` 블록이 있을 수 있습니다. 그러나 대부분의 도구 사용 모델은 이를 무시하므로 이는 선택 사항입니다.
+
+
+### 도구 결과를 모델에 전달하기[[passing-tool-results-to-the-model]]
+
+위의 예제 코드는 모델에 사용할 수 있는 도구를 나열하는 데 충분하지만, 실제로 사용하고자 하는 경우는 어떻게 해야 할까요? 이러한 경우에는 다음을 수행해야 합니다:
+
+1. 모델의 출력을 파싱하여 도구 이름과 인수를 가져옵니다.
+2. 모델의 도구 호출을 대화에 추가합니다.
+3. 해당 인수에 대응하는 함수를 호출합니다.
+4. 결과를 대화에 추가합니다.
+
+### 도구 사용 예제[[a-complete-tool-use-example]]
+
+도구 사용 예제를 단계별로 살펴보겠습니다. 이 예제에서는 도구 사용 모델 중에서 성능이 가장 우수한 8B `Hermes-2-Pro` 모델을 사용할 것입니다. 메모리가 충분하다면, 더 큰 모델인 [Command-R](https://huggingface.co/CohereForAI/c4ai-command-r-v01) 또는 [Mixtral-8x22B](https://huggingface.co/mistralai/Mixtral-8x22B-Instruct-v0.1)를 사용하는 것도 고려할 수 있습니다. 이 두 모델 모두 도구 사용을 지원하며 더 강력한 성능을 제공합니다.
+
+먼저 모델과 토크나이저를 로드해 보겠습니다:
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+checkpoint = "NousResearch/Hermes-2-Pro-Llama-3-8B"
+
+tokenizer = AutoTokenizer.from_pretrained(checkpoint, revision="pr/13")
+model = AutoModelForCausalLM.from_pretrained(checkpoint, torch_dtype=torch.bfloat16, device_map="auto")
+```
+
+다음으로, 도구 목록을 정의해 보겠습니다:
+
+```python
+def get_current_temperature(location: str, unit: str) -> float:
+ """
+ 특정 위치의 현재 온도를 가져옵니다.
+
+ 인수:
+ 위치: 온도를 가져올 위치, "도시, 국가" 형식
+ 단위: 온도 단위 (선택지: ["celsius", "fahrenheit"])
+ 반환값:
+ 지정된 위치의 현재 온도를 지정된 단위로 반환, float 형식.
+ """
+ return 22. # 이 함수는 실제로 온도를 가져와야 할 것입니다!
+
+def get_current_wind_speed(location: str) -> float:
+ """
+ 주어진 위치의 현재 풍속을 km/h 단위로 가져옵니다.
+
+ 인수:
+ 위치(location): 풍속을 가져올 위치, "도시, 국가" 형식
+ 반환값:
+ 주어진 위치의 현재 풍속을 km/h 단위로 반환, float 형식.
+ """
+ return 6. # 이 함수는 실제로 풍속을 가져와야 할 것입니다!
+
+tools = [get_current_temperature, get_current_wind_speed]
+```
+
+이제 봇을 위한 대화를 설정해 보겠습니다:
+
+```python
+messages = [
+ {"role": "system", "content": "You are a bot that responds to weather queries. You should reply with the unit used in the queried location."},
+ {"role": "user", "content": "Hey, what's the temperature in Paris right now?"}
+]
+```
+
+이제 채팅 템플릿을 적용하고 응답을 생성해 보겠습니다:
+
+```python
+inputs = tokenizer.apply_chat_template(messages, chat_template="tool_use", tools=tools, add_generation_prompt=True, return_dict=True, return_tensors="pt")
+inputs = {k: v.to(model.device) for k, v in inputs.items()}
+out = model.generate(**inputs, max_new_tokens=128)
+print(tokenizer.decode(out[0][len(inputs["input_ids"][0]):]))
+```
+
+결과는 다음과 같습니다:
+
+```text
+
+{"arguments": {"location": "Paris, France", "unit": "celsius"}, "name": "get_current_temperature"}
+ <|im_end|>
+```
+
+모델이 함수 호출을 유효한 인수로 수행했으며, 함수 도크스트링에 요청된 형식으로 호출했음을 알 수 있습니다. 모델은 우리가 프랑스의 파리를 지칭하고 있다는 것을 추론했고, 프랑스가 SI 단위의 본고장임을 기억하여 온도를 섭씨로 표시해야 한다고 판단했습니다.
+
+모델의 도구 호출을 대화에 추가해 보겠습니다. 여기서 임의의 `tool_call_id`를 생성합니다. 이 ID는 모든 모델에서 사용되는 것은 아니지만, 여러 도구 호출을 한 번에 발행하고 각 응답이 어느 호출에 해당하는지 추적할 수 있게 해줍니다. 이 ID는 대화 내에서 고유해야 합니다.
+
+```python
+tool_call_id = "vAHdf3" # 임의의 ID, 각 도구 호출마다 고유해야 함
+tool_call = {"name": "get_current_temperature", "arguments": {"location": "Paris, France", "unit": "celsius"}}
+messages.append({"role": "assistant", "tool_calls": [{"id": tool_call_id, "type": "function", "function": tool_call}]})
+```
+
+
+이제 도구 호출을 대화에 추가했으므로, 함수를 호출하고 결과를 대화에 추가할 수 있습니다. 이 예제에서는 항상 22.0을 반환하는 더미 함수를 사용하고 있으므로, 결과를 직접 추가하면 됩니다. 다시 한 번, `tool_call_id`는 도구 호출에 사용했던 ID와 일치해야 합니다.
+
+```python
+messages.append({"role": "tool", "tool_call_id": tool_call_id, "name": "get_current_temperature", "content": "22.0"})
+```
+
+마지막으로, 어시스턴트가 함수 출력을 읽고 사용자와 계속 대화할 수 있도록 하겠습니다:
+
+```python
+inputs = tokenizer.apply_chat_template(messages, chat_template="tool_use", tools=tools, add_generation_prompt=True, return_dict=True, return_tensors="pt")
+inputs = {k: v.to(model.device) for k, v in inputs.items()}
+out = model.generate(**inputs, max_new_tokens=128)
+print(tokenizer.decode(out[0][len(inputs["input_ids"][0]):]))
+```
+
+결과는 다음과 같습니다:
+
+```text
+The current temperature in Paris, France is 22.0 ° Celsius.<|im_end|>
+```
+
+이것은 더미 도구와 단일 호출을 사용한 간단한 데모였지만, 동일한 기술을 사용하여 여러 실제 도구와 더 긴 대화를 처리할 수 있습니다. 이를 통해 실시간 정보, 계산 도구 또는 대규모 데이터베이스에 접근하여 대화형 에이전트의 기능을 확장할 수 있습니다.
+
+
+위에서 보여준 도구 호출 기능은 모든 모델에서 사용되는 것은 아닙니다. 일부 모델은 도구 호출 ID를 사용하고, 일부는 함수 이름만 사용하여 결과와 도구 호출을 순서에 따라 매칭하며, 혼동을 피하기 위해 한 번에 하나의 도구 호출만 발행하는 모델도 있습니다. 가능한 많은 모델과 호환되는 코드를 원한다면, 여기에 보여준 것처럼 도구 호출을 구성하고, 모델이 발행한 순서대로 도구 결과를 반환하는 것을 권장합니다. 각 모델의 채팅 템플릿이 나머지 작업을 처리할 것입니다.
+
+
+### 도구 스키마 이해하기[[understanding-tool-schemas]]
+
+`apply_chat_template`의 `tools` 인수에 전달하는 각 함수는 [JSON 스키마](https://json-schema.org/learn/getting-started-step-by-step)로 변환됩니다. 이러한 스키마는 모델 채팅 템플릿에 전달됩니다. 즉, 도구 사용 모델은 함수 자체를 직접 보지 않으며, 함수 내부의 실제 코드를 보지 않습니다. 도구 사용 모델이 관심을 가지는 것은 함수 **정의**와 **인수**입니다. 함수가 무엇을 하고 어떻게 사용하는지에 관심이 있을 뿐, 어떻게 작동하는지는 중요하지 않습니다! 모델의 출력을 읽고 모델이 도구 사용을 요청했는지 감지하여, 인수를 도구 함수에 전달하고 채팅에서 응답을 반환하는 것은 여러분의 몫입니다.
+
+위의 규격을 따른다면, 템플릿에 전달할 JSON 스키마 생성을 자동화하고 보이지 않게 처리하는 것이 좋습니다. 그러나 문제가 발생하거나 변환을 더 제어하고 싶다면 수동으로 변환을 처리할 수 있습니다. 다음은 수동 스키마 변환 예제입니다.
+
+```python
+from transformers.utils import get_json_schema
+
+def multiply(a: float, b: float):
+ """
+ 두 숫자를 곱하는 함수
+
+ 인수:
+ a: 곱할 첫 번째 숫자
+ b: 곱할 두 번째 숫자
+ """
+ return a * b
+
+schema = get_json_schema(multiply)
+print(schema)
+```
+
+이 결과는 다음과 같습니다:
+
+```json
+{
+ "type": "function",
+ "function": {
+ "name": "multiply",
+ "description": "A function that multiplies two numbers",
+ "parameters": {
+ "type": "object",
+ "properties": {
+ "a": {
+ "type": "number",
+ "description": "The first number to multiply"
+ },
+ "b": {
+ "type": "number",
+ "description": "The second number to multiply"
+ }
+ },
+ "required": ["a", "b"]
+ }
+ }
+}
+```
+
+원한다면 이러한 스키마를 편집하거나 `get_json_schema`를 전혀 사용하지 않고 처음부터 직접 작성할 수도 있습니다. JSON 스키마는 `apply_chat_template`의 `tools` 인수에 직접 전달할 수 있습니다. 이를 통해 더 복잡한 함수에 대한 정밀한 스키마를 정의할 수 있게 됩니다. 그러나 스키마가 복잡할수록 모델이 처리하는 데 혼란을 겪을 가능성이 높아집니다! 가능한 한 간단한 함수 서명을 유지하고, 인수(특히 복잡하고 중첩된 인수)를 최소화하는 것을 권장합니다.
+
+여기 직접 스키마를 정의하고 이를 `apply_chat_template`에 전달하는 예제가 있습니다:
+
+```python
+# 인수를 받지 않는 간단한 함수
+current_time = {
+ "type": "function",
+ "function": {
+ "name": "current_time",
+ "description": "Get the current local time as a string.",
+ "parameters": {
+ 'type': 'object',
+ 'properties': {}
+ }
+ }
+}
+
+# 두 개의 숫자 인수를 받는 더 완전한 함수
+multiply = {
+ 'type': 'function',
+ 'function': {
+ 'name': 'multiply',
+ 'description': 'A function that multiplies two numbers',
+ 'parameters': {
+ 'type': 'object',
+ 'properties': {
+ 'a': {
+ 'type': 'number',
+ 'description': 'The first number to multiply'
+ },
+ 'b': {
+ 'type': 'number', 'description': 'The second number to multiply'
+ }
+ },
+ 'required': ['a', 'b']
+ }
+ }
+}
+
+model_input = tokenizer.apply_chat_template(
+ messages,
+ tools = [current_time, multiply]
+)
+```
+
+## 고급: 검색 증강 생성[[advanced-retrieval-augmented-generation]]
+
+"검색 증강 생성" 또는 "RAG" LLM은 쿼리에 응답하기 전에 문서의 코퍼스를 검색하여 정보를 얻을 수 있습니다. 이를 통해 모델은 제한된 컨텍스트 크기 이상으로 지식 기반을 크게 확장할 수 있습니다. RAG 모델에 대한 우리의 권장 사항은 템플릿이 `documents` 인수를 허용해야 한다는 것입니다. 이 인수는 각 "문서"가 `title`과 `contents` 키를 가지는 단일 dict인 문서 목록이어야 합니다. 이 형식은 도구에 사용되는 JSON 스키마보다 훨씬 간단하므로 별도의 도우미 함수가 필요하지 않습니다.
+
+
+다음은 RAG 템플릿이 작동하는 예제입니다:
+
+
+```python
+document1 = {
+ "title": "The Moon: Our Age-Old Foe",
+ "contents": "Man has always dreamed of destroying the moon. In this essay, I shall..."
+}
+
+document2 = {
+ "title": "The Sun: Our Age-Old Friend",
+ "contents": "Although often underappreciated, the sun provides several notable benefits..."
+}
+
+model_input = tokenizer.apply_chat_template(
+ messages,
+ documents=[document1, document2]
+)
+```
+
+## 고급: 채팅 템플릿은 어떻게 작동하나요?[[advanced-how-do-chat-templates-work]]
+
+모델의 채팅 템플릿은 `tokenizer.chat_template` 속성에 저장됩니다. 채팅 템플릿이 설정되지 않은 경우 해당 모델 클래스의 기본 템플릿이 대신 사용됩니다. `BlenderBot`의 템플릿을 살펴보겠습니다:
+
+```python
+
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/blenderbot-400M-distill")
+
+>>> tokenizer.chat_template
+"{% for message in messages %}{% if message['role'] == 'user' %}{{ ' ' }}{% endif %}{{ message['content'] }}{% if not loop.last %}{{ ' ' }}{% endif %}{% endfor %}{{ eos_token }}"
+```
+
+약간 복잡해 보일 수 있습니다. 읽기 쉽게 정리해 보겠습니다. 이 과정에서 추가하는 줄바꿈과 들여쓰기가 템플릿 출력에 포함되지 않도록 해야 합니다. 아래는 [공백을 제거하는](#trimming-whitespace) 팁입니다:
+
+```
+{%- for message in messages %}
+ {%- if message['role'] == 'user' %}
+ {{- ' ' }}
+ {%- endif %}
+ {{- message['content'] }}
+ {%- if not loop.last %}
+ {{- ' ' }}
+ {%- endif %}
+{%- endfor %}
+{{- eos_token }}
+```
+
+만약 이와 같은 형식을 처음 본다면, 이것은 [Jinja 템플릿](https://jinja.palletsprojects.com/en/3.1.x/templates/)입니다.
+Jinja는 텍스트를 생성하는 간단한 코드를 작성할 수 있는 템플릿 언어입니다. 많은 면에서 코드와 구문이 파이썬과 유사합니다. 순수 파이썬에서는 이 템플릿이 다음과 같이 보일 것입니다:
+
+
+```python
+for idx, message in enumerate(messages):
+ if message['role'] == 'user':
+ print(' ')
+ print(message['content'])
+ if not idx == len(messages) - 1: # Check for the last message in the conversation
+ print(' ')
+print(eos_token)
+```
+
+이 템플릿은 세 가지 일을 합니다:
+1. 각 메시지에 대해, 메시지가 사용자 메시지인 경우 공백을 추가하고, 그렇지 않으면 아무것도 출력하지 않습니다.
+2. 메시지 내용을 추가합니다.
+3. 메시지가 마지막 메시지가 아닌 경우 두 개의 공백을 추가합니다. 마지막 메시지 후에는 EOS 토큰을 출력합니다.
+
+이것은 매우 간단한 템플릿입니다. 제어 토큰을 추가하지 않으며, 이후 대화에서 모델이 어떻게 동작해야 하는지 지시하는 "시스템" 메시지를 지원하지 않습니다. 하지만 Jinja는 이러한 작업을 수행할 수 있는 많은 유연성을 제공합니다! LLaMA가 입력을 형식화하는 방식과 유사한 형식의 Jinja 템플릿을 살펴보겠습니다(실제 LLaMA 템플릿은 기본 시스템 메시지 처리와 일반적인 시스템 메시지 처리를 포함하고 있습니다 - 실제 코드에서는 이 템플릿을 사용하지 마세요!).
+
+```
+{%- for message in messages %}
+ {%- if message['role'] == 'user' %}
+ {{- bos_token + '[INST] ' + message['content'] + ' [/INST]' }}
+ {%- elif message['role'] == 'system' %}
+ {{- '<>\\n' + message['content'] + '\\n< >\\n\\n' }}
+ {%- elif message['role'] == 'assistant' %}
+ {{- ' ' + message['content'] + ' ' + eos_token }}
+ {%- endif %}
+{%- endfor %}
+```
+
+이 템플릿을 잠시 살펴보면 무엇을 하는지 이해할 수 있습니다. 먼저, 각 메시지의 "role"에 따라 특정 토큰을 추가하여 누가 메시지를 보냈는지 모델에게 명확하게 알려줍니다. 또한 사용자, 어시스턴트 및 시스템 메시지는 각각 고유한 토큰으로 래핑되어 모델이 명확하게 구분할 수 있습니다.
+
+## 고급: 채팅 템플릿 추가 및 편집[[advanced-adding-and-editing-chat-templates]]
+
+### 채팅 템플릿을 어떻게 만들 수 있나요?[[how-do-i-create-a-chat-template]]
+
+간단합니다. Jinja 템플릿을 작성하고 `tokenizer.chat_template`에 설정하기만 하면 됩니다. 다른 모델의 기존 템플릿을 시작점으로 사용하고 필요에 맞게 편집하는 것이 더 쉬울 것 입니다! 예를 들어, 위의 LLaMA 템플릿을 가져와 어시스턴트 메시지에 "[ASST]" 및 "[/ASST]"를 추가할 수 있습니다:
+
+```
+{%- for message in messages %}
+ {%- if message['role'] == 'user' %}
+ {{- bos_token + '[INST] ' + message['content'].strip() + ' [/INST]' }}
+ {%- elif message['role'] == 'system' %}
+ {{- '<>\\n' + message['content'].strip() + '\\n< >\\n\\n' }}
+ {%- elif message['role'] == 'assistant' %}
+ {{- '[ASST] ' + message['content'] + ' [/ASST]' + eos_token }}
+ {%- endif %}
+{%- endfor %}
+```
+
+이제 `tokenizer.chat_template` 속성을 설정하기만 하면 됩니다. 이렇게 하면 다음에 [`~PreTrainedTokenizer.apply_chat_template`]를 사용할 때 새롭게 설정한 템플릿이 사용됩니다! 이 속성은 `tokenizer_config.json` 파일에 저장되므로, [`~utils.PushToHubMixin.push_to_hub`]를 사용하여 새 템플릿을 허브에 업로드하고 모든 사용자가 모델에 맞는 템플릿을 사용할 수 있도록 할 수 있습니다!
+
+```python
+template = tokenizer.chat_template
+template = template.replace("SYS", "SYSTEM") # 시스템 토큰 변경
+tokenizer.chat_template = template # 새 템플릿 설정
+tokenizer.push_to_hub("model_name") # 새 템플릿을 허브에 업로드!
+```
+
+채팅 템플릿을 사용하는 [`~PreTrainedTokenizer.apply_chat_template`] 메소드는 [`TextGenerationPipeline`] 클래스에서 호출되므로, 올바른 채팅 템플릿을 설정하면 모델이 자동으로 [`TextGenerationPipeline`]과 호환됩니다.
+
+
+모델을 채팅 용도로 미세 조정하는 경우, 채팅 템플릿을 설정하는 것 외에도 새 채팅 제어 토큰을 토크나이저에 특별 토큰으로 추가하는 것이 좋습니다. 특별 토큰은 절대로 분할되지 않으므로, 제어 토큰이 여러 조각으로 토큰화되는 것을 방지합니다. 또한, 템플릿에서 어시스턴트 생성의 끝을 나타내는 토큰으로 토크나이저의 `eos_token` 속성을 설정해야 합니다. 이렇게 하면 텍스트 생성 도구가 텍스트 생성을 언제 중지해야 할지 정확히 알 수 있습니다.
+
+
+
+### 왜 일부 모델은 여러 개의 템플릿을 가지고 있나요?[[why-do-some-models-have-multiple-templates]]
+
+일부 모델은 다른 사용 사례에 대해 다른 템플릿을 사용합니다. 예를 들어, 일반 채팅을 위한 템플릿과 도구 사용 또는 검색 증강 생성에 대한 템플릿을 별도로 사용할 수 있습니다. 이러한 경우 `tokenizer.chat_template`는 딕셔너리입니다. 이것은 약간의 혼란을 초래할 수 있으며, 가능한 한 모든 사용 사례에 대해 단일 템플릿을 사용하는 것을 권장합니다. `if tools is defined`와 같은 Jinja 문장과 `{% macro %}` 정의를 사용하여 여러 코드 경로를 단일 템플릿에 쉽게 래핑할 수 있습니다.
+
+토크나이저에 여러 개의 템플릿이 있는 경우, `tokenizer.chat_template`는 템플릿 이름이 키인 `딕셔너리`입니다. `apply_chat_template` 메소드는 특정 템플릿 이름에 대한 특별한 처리를 합니다: 일반적으로 `default`라는 템플릿을 찾고, 찾을 수 없으면 오류를 발생시킵니다. 그러나 사용자가 `tools` 인수를 전달할 때 `tool_use`라는 템플릿이 존재하면 대신 그것을 사용합니다. 다른 이름의 템플릿에 접근하려면 `apply_chat_template()`의 `chat_template` 인수에 원하는 템플릿 이름을 전달하면 됩니다.
+
+사용자에게 약간의 혼란을 줄 수 있으므로, 템플릿을 직접 작성하는 경우 가능한 한 단일 템플릿에 모든 것을 넣는 것을 권장합니다!
+
+### 어떤 템플릿을 사용해야 하나요?[[what-template-should-i-use]]
+
+이미 채팅용으로 훈련된 모델에 템플릿을 설정할 때는 템플릿이 훈련 중 모델이 본 메시지 형식과 정확히 일치하도록 해야 합니다. 그렇지 않으면 성능 저하를 경험할 가능성이 큽니다. 이는 모델을 추가로 훈련할 때도 마찬가지입니다. 채팅 토큰을 일정하게 유지하는 것이 최상의 성능을 얻는 방법입니다. 이는 토큰화와 매우 유사합니다. 훈련 중에 사용된 토큰화를 정확히 일치시킬 때 추론이나 미세 조정에서 최고의 성능을 얻을 수 있습니다.
+
+반면에 처음부터 모델을 훈련시키거나 채팅용으로 기본 언어 모델을 미세 조정하는 경우, 적절한 템플릿을 선택할 수 있는 많은 자유가 있습니다. LLM은 다양한 입력 형식을 처리할 만큼 충분히 똑똑합니다. 인기 있는 선택 중 하나는 `ChatML` 형식이며, 이는 많은 사용 사례에 유연하게 사용할 수 있는 좋은 선택입니다. 다음과 같습니다:
+
+```
+{%- for message in messages %}
+ {{- '<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n' }}
+{%- endfor %}
+```
+
+이 템플릿이 마음에 든다면, 코드에 바로 복사하여 사용할 수 있는 한 줄 버전을 제공하겠습니다. 이 한 줄 버전은 [생성 프롬프트](#what-are-generation-prompts)에 대한 편리한 지원도 포함하고 있지만, BOS나 EOS 토큰을 추가하지 않는다는 점에 유의하세요! 모델이 해당 토큰을 기대하더라도, `apply_chat_template`에 의해 자동으로 추가되지 않습니다. 즉, 텍스트는 `add_special_tokens=False`에 의해 토큰화됩니다. 이는 템플릿과 `add_special_tokens` 논리 간의 잠재적인 충돌을 피하기 위함입니다. 모델이 특별 토큰을 기대하는 경우, 템플릿에 직접 추가해야 합니다!
+
+
+```python
+tokenizer.chat_template = "{% if not add_generation_prompt is defined %}{% set add_generation_prompt = false %}{% endif %}{% for message in messages %}{{'<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n'}}{% endfor %}{% if add_generation_prompt %}{{ '<|im_start|>assistant\n' }}{% endif %}"
+```
+
+이 템플릿은 각 메시지를 `<|im_start|>` 와 `<|im_end|>`토큰으로 감싸고, 역할을 문자열로 작성하여 훈련 시 사용하는 역할에 대한 유연성을 제공합니다. 출력은 다음과 같습니다:
+
+
+```text
+<|im_start|>system
+You are a helpful chatbot that will do its best not to say anything so stupid that people tweet about it.<|im_end|>
+<|im_start|>user
+How are you?<|im_end|>
+<|im_start|>assistant
+I'm doing great!<|im_end|>
+```
+
+"사용자", "시스템" 및 "어시스턴트" 역할은 채팅의 표준이며, 가능할 때 이를 사용하는 것을 권장합니다. 특히 모델이 [`TextGenerationPipeline`]과 잘 작동하도록 하려면 그렇습니다. 그러나 이러한 역할에만 국한되지 않습니다. 템플릿은 매우 유연하며, 어떤 문자열이든 역할로 사용할 수 있습니다.
+
+
+
+### 채팅 템플릿을 추가하고 싶습니다! 어떻게 시작해야 하나요?[[i-want-to-add-some-chat-templates-how-should-i-get-started]]
+
+채팅 모델이 있는 경우, 해당 모델의 `tokenizer.chat_template` 속성을 설정하고 [`~PreTrainedTokenizer.apply_chat_template`]를 사용하여 테스트한 다음 업데이트된 토크나이저를 허브에 푸시해야 합니다. 이는 모델 소유자가 아닌 경우에도 적용됩니다. 빈 채팅 템플릿을 사용하는 모델이나 여전히 기본 클래스 템플릿을 사용하는 모델을 사용하는 경우, [풀 리퀘스트](https://huggingface.co/docs/hub/repositories-pull-requests-discussions)를 모델 리포지토리에 열어 이 속성을 올바르게 설정할 수 있도록 하세요!
+
+속성을 설정하면 끝입니다! `tokenizer.apply_chat_template`가 이제 해당 모델에 대해 올바르게 작동하므로, `TextGenerationPipeline`과 같은 곳에서도 자동으로 지원됩니다!
+
+모델에 이 속성을 설정함으로써, 오픈 소스 모델의 전체 기능을 커뮤니티가 사용할 수 있도록 할 수 있습니다. 형식 불일치는 이 분야에서 오랫동안 성능을 저하시키는 문제였으므로, 이제 이를 끝낼 때입니다!
+
+## 고급: 템플릿 작성 팁[[advanced-template-writing-tips]]
+
+Jinja에 익숙하지 않은 경우, 채팅 템플릿을 작성하는 가장 쉬운 방법은 먼저 메시지를 원하는 방식으로 형식화하는 짧은 파이썬 스크립트를 작성한 다음, 해당 스크립트를 템플릿으로 변환하는 것입니다.
+
+템플릿 핸들러는 `messages`라는 변수로 대화 기록을 받습니다. 파이썬에서와 마찬가지로 템플릿 내의 `messages`에 접근할 수 있으며, `{% for message in messages %}`로 반복하거나 `{{ messages[0] }}`와 같이 개별 메시지에 접근할 수 있습니다.
+
+다음 팁을 사용하여 코드를 Jinja로 변환할 수도 있습니다:
+
+### 공백 제거[[trimming-whitespace]]
+
+기본적으로 Jinja는 블록 전후의 공백을 출력합니다. 이는 일반적으로 공백을 매우 정확하게 다루고자 하는 채팅 템플릿에서는 문제가 될 수 있습니다! 이를 피하기 위해 템플릿을 다음과 같이 작성하는 것이 좋습니다:
+
+```
+{%- for message in messages %}
+ {{- message['role'] + message['content'] }}
+{%- endfor %}
+```
+
+아래와 같이 작성하지 마세요:
+
+```
+{% for message in messages %}
+ {{ message['role'] + message['content'] }}
+{% endfor %}
+```
+
+`-`를 추가하면 블록 전후의 공백이 제거됩니다. 두 번째 예제는 무해해 보이지만, 줄바꿈과 들여쓰기가 출력에 포함될 수 있으며, 이는 원하지 않는 결과일 수 있습니다!
+
+### 반복문[[for-loops]]
+
+Jinja에서 반복문은 다음과 같습니다:
+
+```
+{%- for message in messages %}
+ {{- message['content'] }}
+{%- endfor %}
+```
+
+{{ 표현식 블록 }} 내부에 있는 모든 것이 출력으로 인쇄됩니다. `+`와 같은 연산자를 사용하여 표현식 블록 내부에서 문자열을 결합할 수 있습니다.
+
+### 조건문[[if-statements]]
+
+Jinja에서 조건문은 다음과 같습니다:
+
+```
+{%- if message['role'] == 'user' %}
+ {{- message['content'] }}
+{%- endif %}
+```
+
+파이썬이 공백을 사용하여 `for` 및 `if` 블록의 시작과 끝을 표시하는 반면, Jinja는 `{% endfor %}` 및 `{% endif %}`로 명시적으로 끝을 표시해야 합니다.
+
+### 특수 변수[[special-variables]]
+
+템플릿 내부에서는 `messages` 목록에 접근할 수 있을 뿐만 아니라 여러 다른 특수 변수에도 접근할 수 있습니다. 여기에는 `bos_token` 및 `eos_token`과 같은 특별 토큰과 앞서 논의한 `add_generation_prompt` 변수가 포함됩니다. 또한 `loop` 변수를 사용하여 현재 반복에 대한 정보를 얻을 수 있으며, 예를 들어 `{% if loop.last %}`를 사용하여 현재 메시지가 대화의 마지막 메시지인지 확인할 수 있습니다. `add_generation_prompt`가 `True`인 경우 대화 끝에 생성 프롬프트를 추가하는 예제는 다음과 같습니다:
+
+```
+{%- if loop.last and add_generation_prompt %}
+ {{- bos_token + 'Assistant:\n' }}
+{%- endif %}
+```
+
+### 비파이썬 Jinja와의 호환성[[compatibility-with-non-python-jinja]]
+
+Jinja의 여러 구현은 다양한 언어로 제공됩니다. 일반적으로 동일한 구문을 사용하지만, 주요 차이점은 파이썬에서 템플릿을 작성할 때 파이썬 메소드를 사용할 수 있다는 점입니다. 예를 들어, 문자열에 `.lower()`를 사용하거나 딕셔너리에 `.items()`를 사용하는 것입니다. 이는 비파이썬 Jinja 구현에서 템플릿을 사용하려고 할 때 문제가 발생할 수 있습니다. 특히 JS와 Rust가 인기 있는 배포 환경에서는 비파이썬 구현이 흔합니다.
+
+하지만 걱정하지 마세요! 모든 Jinja 구현에서 호환성을 보장하기 위해 템플릿을 쉽게 변경할 수 있는 몇 가지 방법이 있습니다:
+
+- 파이썬 메소드를 Jinja 필터로 대체하세요. 일반적으로 같은 이름을 가지며, 예를 들어 `string.lower()`는 `string|lower`로, `dict.items()`는 `dict|items`로 대체할 수 있습니다. 주목할 만한 변경 사항은 `string.strip()`이 `string|trim`으로 바뀌는 것입니다. 더 자세한 내용은 Jinja 문서의 [내장 필터 목록](https://jinja.palletsprojects.com/en/3.1.x/templates/#builtin-filters)을 참조하세요.
+- 파이썬에 특화된 `True`, `False`, `None`을 각각 `true`, `false`, `none`으로 대체하세요.
+- 딕셔너리나 리스트를 직접 렌더링할 때 다른 구현에서는 결과가 다를 수 있습니다(예: 문자열 항목이 단일 따옴표에서 이중 따옴표로 변경될 수 있습니다). `tojson` 필터를 추가하면 일관성을 유지하는 데 도움이 됩니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/community.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/community.md
new file mode 100644
index 0000000000000000000000000000000000000000..d50168d7548620805d06b2aa06190bbbc8d4d936
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/community.md
@@ -0,0 +1,69 @@
+
+
+# 커뮤니티 [[community]]
+
+이 페이지는 커뮤니티에서 개발한 🤗 Transformers 리소스를 재구성한 페이지입니다.
+
+## 커뮤니티 리소스: [[community-resources]]
+
+| 리소스 | 설명 | 만든이 |
+|:----------|:-------------|------:|
+| [Hugging Face Transformers 용어집 플래시카드](https://www.darigovresearch.com/huggingface-transformers-glossary-flashcards) | [Transformers 문서 용어집](glossary)을 기반으로 한 플래시카드 세트로, 지식을 장기적으로 유지하기 위해 특별히 설계된 오픈소스 크로스 플랫폼 앱인 [Anki](https://apps.ankiweb.net/)를 사용하여 쉽게 학습/수정할 수 있는 형태로 제작되었습니다. [플래시카드 사용법에 대한 소개 동영상](https://www.youtube.com/watch?v=Dji_h7PILrw)을 참조하세요. | [Darigov 리서치](https://www.darigovresearch.com/) |
+
+## 커뮤니티 노트북: [[community-notebooks]]
+
+| 노트북 | 설명 | 만든이 | |
+|:----------|:-------------|:-------------|------:|
+| [가사를 생성하기 위해 사전훈련된 트랜스포머를 미세 조정하기](https://github.com/AlekseyKorshuk/huggingartists) | GPT-2 모델을 미세 조정하여 좋아하는 아티스트의 스타일로 가사를 생성하는 방법 | [Aleksey Korshuk](https://github.com/AlekseyKorshuk) | [](https://colab.research.google.com/github/AlekseyKorshuk/huggingartists/blob/master/huggingartists-demo.ipynb) |
+| [Tensorflow 2로 T5 훈련하기](https://github.com/snapthat/TF-T5-text-to-text) | Tensorflow 2를 사용하여 T5를 훈련시키는 방법. 이 노트북은 Tensorflow 2로 SQUAD를 사용하여 구현한 질의응답 작업을 보여줍니다. | [Muhammad Harris](https://github.com/HarrisDePerceptron) |[](https://colab.research.google.com/github/snapthat/TF-T5-text-to-text/blob/master/snapthatT5/notebooks/TF-T5-Datasets%20Training.ipynb) |
+| [TPU에서 T5 훈련하기](https://github.com/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb) | Transformers와 Nlp를 사용하여 SQUAD로 T5를 훈련하는 방법 | [Suraj Patil](https://github.com/patil-suraj) |[](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb#scrollTo=QLGiFCDqvuil) |
+| [분류 및 객관식 문제를 위해 T5 미세 조정하기](https://github.com/patil-suraj/exploring-T5/blob/master/t5_fine_tuning.ipynb) | 분류 및 객관식 문제에 맞게 텍스트-텍스트 형식을 사용하여 PyTorch Lightning으로 T5를 미세 조정하는 방법 | [Suraj Patil](https://github.com/patil-suraj) | [](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/t5_fine_tuning.ipynb) |
+| [새로운 데이터 세트와 언어로 DialoGPT 미세 조정하기](https://github.com/ncoop57/i-am-a-nerd/blob/master/_notebooks/2020-05-12-chatbot-part-1.ipynb) | 자유 대화형 챗봇을 만들기 위해 새로운 데이터 세트로 DialoGPT 모델을 미세 조정하는 방법 | [Nathan Cooper](https://github.com/ncoop57) | [](https://colab.research.google.com/github/ncoop57/i-am-a-nerd/blob/master/_notebooks/2020-05-12-chatbot-part-1.ipynb) |
+| [Reformer로 긴 시퀀스 모델링하기](https://github.com/patrickvonplaten/notebooks/blob/master/PyTorch_Reformer.ipynb) | Reformer로 최대 50만 토큰의 시퀀스를 훈련하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/PyTorch_Reformer.ipynb) |
+| [요약을 위해 BART 미세 조정하기](https://github.com/ohmeow/ohmeow_website/blob/master/posts/2021-05-25-mbart-sequence-classification-with-blurr.ipynb) | blurr를 사용하여 fastai로 요약하기 위해 BART를 미세 조정하는 방법 | [Wayde Gilliam](https://ohmeow.com/) | [](https://colab.research.google.com/github/ohmeow/ohmeow_website/blob/master/posts/2021-05-25-mbart-sequence-classification-with-blurr.ipynb) |
+| [다른 사람의 트윗으로 사전훈련된 트랜스포머 미세 조정하기](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb) | GPT-2 모델을 미세 조정하여 좋아하는 트위터 계정 스타일로 트윗을 생성하는 방법 | [Boris Dayma](https://github.com/borisdayma) | [](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb) |
+| [Weights & Biases로 🤗 Hugging Face 모델 최적화하기](https://colab.research.google.com/github/wandb/examples/blob/master/colabs/huggingface/Optimize_Hugging_Face_models_with_Weights_%26_Biases.ipynb) | W&B와 Hugging Face의 통합을 보여주는 전체 튜토리얼 | [Boris Dayma](https://github.com/borisdayma) | [](https://colab.research.google.com/github/wandb/examples/blob/master/colabs/huggingface/Optimize_Hugging_Face_models_with_Weights_%26_Biases.ipynb) |
+| [Longformer 사전훈련하기](https://github.com/allenai/longformer/blob/master/scripts/convert_model_to_long.ipynb) | 기존 사전훈련된 모델의 "긴" 버전을 빌드하는 방법 | [Iz Beltagy](https://beltagy.net) | [](https://colab.research.google.com/github/allenai/longformer/blob/master/scripts/convert_model_to_long.ipynb) |
+| [QA를 위해 Longformer 미세 조정하기](https://github.com/patil-suraj/Notebooks/blob/master/longformer_qa_training.ipynb) | QA 작업을 위해 Longformer를 미세 조정하는 방법 | [Suraj Patil](https://github.com/patil-suraj) | [](https://colab.research.google.com/github/patil-suraj/Notebooks/blob/master/longformer_qa_training.ipynb) |
+| [🤗 Nlp로 모델 평가하기](https://github.com/patrickvonplaten/notebooks/blob/master/How_to_evaluate_Longformer_on_TriviaQA_using_NLP.ipynb) | `Nlp`로 TriviaQA에서 Longformer를 평가하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/drive/1m7eTGlPmLRgoPkkA7rkhQdZ9ydpmsdLE?usp=sharing) |
+| [감정 범위 추출을 위해 T5 미세 조정하기](https://github.com/enzoampil/t5-intro/blob/master/t5_qa_training_pytorch_span_extraction.ipynb) | 감정 범위 추출을 위해 텍스트-텍스트 형식을 사용하여 PyTorch Lightning으로 T5를 미세 조정하는 방법 | [Lorenzo Ampil](https://github.com/enzoampil) | [](https://colab.research.google.com/github/enzoampil/t5-intro/blob/master/t5_qa_training_pytorch_span_extraction.ipynb) |
+| [다중 클래스 분류를 위해 DistilBert 미세 조정하기](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_multiclass_classification.ipynb) | 다중 클래스 분류를 위해 PyTorch를 사용하여 DistilBert를 미세 조정하는 방법 | [Abhishek Kumar Mishra](https://github.com/abhimishra91) | [](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_multiclass_classification.ipynb)|
+| [다중 레이블 분류를 위해 BERT 미세 조정하기](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_multi_label_classification.ipynb) | 다중 레이블 분류를 위해 PyTorch를 사용하여 BERT를 미세 조정하는 방법 | [Abhishek Kumar Mishra](https://github.com/abhimishra91) | [](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_multi_label_classification.ipynb)|
+| [요약을 위해 T5 미세 조정하기](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_summarization_wandb.ipynb) | 요약을 위해 PyTorch로 T5를 미세 조정하고 WandB로 실험을 추적하는 방법 | [Abhishek Kumar Mishra](https://github.com/abhimishra91) | [](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_summarization_wandb.ipynb)|
+| [동적 패딩/버켓팅으로 Transformers 미세 조정 속도 높이기](https://github.com/ELS-RD/transformers-notebook/blob/master/Divide_Hugging_Face_Transformers_training_time_by_2_or_more.ipynb)| 동적 패딩/버켓팅을 사용하여 미세 조정 속도를 2배로 높이는 방법 |[Michael Benesty](https://github.com/pommedeterresautee) |[](https://colab.research.google.com/drive/1CBfRU1zbfu7-ijiOqAAQUA-RJaxfcJoO?usp=sharing)|
+|[마스킹된 언어 모델링을 위해 Reformer 사전훈련하기](https://github.com/patrickvonplaten/notebooks/blob/master/Reformer_For_Masked_LM.ipynb)| 양방향 셀프 어텐션 레이어를 이용해서 Reformer 모델을 훈련하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/drive/1tzzh0i8PgDQGV3SMFUGxM7_gGae3K-uW?usp=sharing)|
+| [Sci-BERT 확장 및 미세 조정하기](https://github.com/lordtt13/word-embeddings/blob/master/COVID-19%20Research%20Data/COVID-SciBERT.ipynb)| CORD 데이터 세트로 AllenAI에서 사전훈련된 SciBERT 모델의 어휘를 늘리고 파이프라인을 구축하는 방법 | [Tanmay Thakur](https://github.com/lordtt13) | [](https://colab.research.google.com/drive/1rqAR40goxbAfez1xvF3hBJphSCsvXmh8)|
+| [요약을 위해 Trainer API로 BlenderBotSmall 미세 조정하기](https://github.com/lordtt13/transformers-experiments/blob/master/Custom%20Tasks/fine-tune-blenderbot_small-for-summarization.ipynb)| 요약을 위해 Trainer API를 사용하여 사용자 지정 데이터 세트로 BlenderBotSmall 미세 조정하기 | [Tanmay Thakur](https://github.com/lordtt13) | [](https://colab.research.google.com/drive/19Wmupuls7mykSGyRN_Qo6lPQhgp56ymq?usp=sharing)|
+| [통합 기울기(Integrated Gradient)를 이용하여 Electra 미세 조정하고 해석하기](https://github.com/elsanns/xai-nlp-notebooks/blob/master/electra_fine_tune_interpret_captum_ig.ipynb) | 감정 분석을 위해 Electra를 미세 조정하고 Captum 통합 기울기로 예측을 해석하는 방법 | [Eliza Szczechla](https://elsanns.github.io) | [](https://colab.research.google.com/github/elsanns/xai-nlp-notebooks/blob/master/electra_fine_tune_interpret_captum_ig.ipynb)|
+| [Trainer 클래스로 비영어권 GPT-2 모델 미세 조정하기](https://github.com/philschmid/fine-tune-GPT-2/blob/master/Fine_tune_a_non_English_GPT_2_Model_with_Huggingface.ipynb) | Trainer 클래스로 비영어권 GPT-2 모델을 미세 조정하는 방법 | [Philipp Schmid](https://www.philschmid.de) | [](https://colab.research.google.com/github/philschmid/fine-tune-GPT-2/blob/master/Fine_tune_a_non_English_GPT_2_Model_with_Huggingface.ipynb)|
+|[다중 라벨 분류 작업을 위해 DistilBERT 모델 미세 조정하기](https://github.com/DhavalTaunk08/Transformers_scripts/blob/master/Transformers_multilabel_distilbert.ipynb) | 다중 라벨 분류 작업을 위해 DistilBERT 모델을 미세 조정하는 방법 | [Dhaval Taunk](https://github.com/DhavalTaunk08) | [](https://colab.research.google.com/github/DhavalTaunk08/Transformers_scripts/blob/master/Transformers_multilabel_distilbert.ipynb)|
+|[문장쌍 분류를 위해 ALBERT 미세 조정하기](https://github.com/NadirEM/nlp-notebooks/blob/master/Fine_tune_ALBERT_sentence_pair_classification.ipynb) | 문장쌍 분류 작업을 위해 ALBERT 모델 또는 다른 BERT 기반 모델을 미세 조정하는 방법 | [Nadir El Manouzi](https://github.com/NadirEM) | [](https://colab.research.google.com/github/NadirEM/nlp-notebooks/blob/master/Fine_tune_ALBERT_sentence_pair_classification.ipynb)|
+|[감정 분석을 위해 Roberta 미세 조정하기](https://github.com/DhavalTaunk08/NLP_scripts/blob/master/sentiment_analysis_using_roberta.ipynb) | 감정 분석을 위해 Roberta 모델을 미세 조정하는 방법 | [Dhaval Taunk](https://github.com/DhavalTaunk08) | [](https://colab.research.google.com/github/DhavalTaunk08/NLP_scripts/blob/master/sentiment_analysis_using_roberta.ipynb)|
+|[질문 생성 모델 평가하기](https://github.com/flexudy-pipe/qugeev) | seq2seq 트랜스포머 모델이 생성한 질문과 이에 대한 답변이 얼마나 정확한가요? | [Pascal Zoleko](https://github.com/zolekode) | [](https://colab.research.google.com/drive/1bpsSqCQU-iw_5nNoRm_crPq6FRuJthq_?usp=sharing)|
+|[DistilBERT와 Tensorflow로 텍스트 분류하기](https://github.com/peterbayerle/huggingface_notebook/blob/main/distilbert_tf.ipynb) | 텍스트 분류를 위해 TensorFlow로 DistilBERT를 미세 조정하는 방법 | [Peter Bayerle](https://github.com/peterbayerle) | [](https://colab.research.google.com/github/peterbayerle/huggingface_notebook/blob/main/distilbert_tf.ipynb)|
+|[CNN/Dailail 요약을 위해 인코더-디코더 모델에 BERT 활용하기](https://github.com/patrickvonplaten/notebooks/blob/master/BERT2BERT_for_CNN_Dailymail.ipynb) | CNN/Dailail 요약을 위해 *google-bert/bert-base-uncased* 체크포인트를 활용하여 *EncoderDecoderModel*을 워밍업하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/BERT2BERT_for_CNN_Dailymail.ipynb)|
+|[BBC XSum 요약을 위해 인코더-디코더 모델에 RoBERTa 활용하기](https://github.com/patrickvonplaten/notebooks/blob/master/RoBERTaShared_for_BBC_XSum.ipynb) | BBC/XSum 요약을 위해 *FacebookAI/roberta-base* 체크포인트를 활용하여 공유 *EncoderDecoderModel*을 워밍업하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/RoBERTaShared_for_BBC_XSum.ipynb)|
+|[순차적 질문 답변(SQA)을 위해 TAPAS 미세 조정하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) | *tapas-base* 체크포인트를 활용하여 순차적 질문 답변(SQA) 데이터 세트로 *TapasForQuestionAnswering*을 미세 조정하는 방법 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb)|
+|[표 사실 검사(TabFact)로 TAPAS 평가하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Evaluating_TAPAS_on_the_Tabfact_test_set.ipynb) | 🤗 Datasets와 🤗 Transformer 라이브러리를 함께 사용하여 *tapas-base-finetuned-tabfact* 체크포인트로 미세 조정된 *TapasForSequenceClassification*을 평가하는 방법 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Evaluating_TAPAS_on_the_Tabfact_test_set.ipynb)|
+|[번역을 위해 mBART 미세 조정하기](https://colab.research.google.com/github/vasudevgupta7/huggingface-tutorials/blob/main/translation_training.ipynb) | 힌디어에서 영어로 번역하기 위해 Seq2SeqTrainer를 사용하여 mBART를 미세 조정하는 방법 | [Vasudev Gupta](https://github.com/vasudevgupta7) | [](https://colab.research.google.com/github/vasudevgupta7/huggingface-tutorials/blob/main/translation_training.ipynb)|
+|[FUNSD(양식 이해 데이터 세트)로 LayoutLM 미세 조정하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb) | 스캔한 문서에서 정보 추출을 위해 FUNSD 데이터 세트로 *LayoutLMForTokenClassification*을 미세 조정하는 방법 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb)|
+|[DistilGPT2 미세 조정하고 및 텍스트 생성하기](https://colab.research.google.com/github/tripathiaakash/DistilGPT2-Tutorial/blob/main/distilgpt2_fine_tuning.ipynb) | DistilGPT2를 미세 조정하고 텍스트를 생성하는 방법 | [Aakash Tripathi](https://github.com/tripathiaakash) | [](https://colab.research.google.com/github/tripathiaakash/DistilGPT2-Tutorial/blob/main/distilgpt2_fine_tuning.ipynb)|
+|[최대 8K 토큰에서 LED 미세 조정하기](https://github.com/patrickvonplaten/notebooks/blob/master/Fine_tune_Longformer_Encoder_Decoder_(LED)_for_Summarization_on_pubmed.ipynb) | 긴 범위를 요약하기 위해 PubMed로 LED를 미세 조정하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/Fine_tune_Longformer_Encoder_Decoder_(LED)_for_Summarization_on_pubmed.ipynb)|
+|[Arxiv로 LED 평가하기](https://github.com/patrickvonplaten/notebooks/blob/master/LED_on_Arxiv.ipynb) | 긴 범위 요약에 대해 LED를 효과적으로 평가하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/LED_on_Arxiv.ipynb)|
+|[RVL-CDIP(문서 이미지 분류 데이터 세트)로 LayoutLM 미세 조정하기)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb) | 스캔 문서 분류를 위해 RVL-CDIP 데이터 세트로 *LayoutLMForSequenceClassification*을 미세 조정하는 방법 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb)|
+|[GPT2 조정을 통한 Wav2Vec2 CTC 디코딩](https://github.com/voidful/huggingface_notebook/blob/main/xlsr_gpt.ipynb) | 언어 모델 조정을 통해 CTC 시퀀스를 디코딩하는 방법 | [Eric Lam](https://github.com/voidful) | [](https://colab.research.google.com/drive/1e_z5jQHYbO2YKEaUgzb1ww1WwiAyydAj?usp=sharing)|
+|[Trainer 클래스로 두 개 언어로 요약하기 위해 BART 미세 조정하기](https://github.com/elsanns/xai-nlp-notebooks/blob/master/fine_tune_bart_summarization_two_langs.ipynb) | Trainer 클래스로 두 개 언어로 요약하기 위해 BART 미세 조정하는 방법 | [Eliza Szczechla](https://github.com/elsanns) | [](https://colab.research.google.com/github/elsanns/xai-nlp-notebooks/blob/master/fine_tune_bart_summarization_two_langs.ipynb)|
+|[Trivia QA로 Big Bird 평가하기](https://github.com/patrickvonplaten/notebooks/blob/master/Evaluating_Big_Bird_on_TriviaQA.ipynb) | Trivia QA로 긴 문서 질문에 대한 답변에 대해 BigBird를 평가하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/Evaluating_Big_Bird_on_TriviaQA.ipynb)|
+| [Wav2Vec2를 사용하여 동영상 캡션 만들기](https://github.com/Muennighoff/ytclipcc/blob/main/wav2vec_youtube_captions.ipynb) | Wav2Vec으로 오디오를 텍스트로 변환하여 모든 동영상에서 YouTube 캡션 만드는 방법 | [Niklas Muennighoff](https://github.com/Muennighoff) |[](https://colab.research.google.com/github/Muennighoff/ytclipcc/blob/main/wav2vec_youtube_captions.ipynb) |
+| [PyTorch Lightning을 사용하여 CIFAR-10으로 비전 트랜스포머 미세 조정하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_PyTorch_Lightning.ipynb) | HuggingFace Transformers, Datasets, PyTorch Lightning을 사용하여 CIFAR-10으로 비전 트랜스포머(ViT)를 미세 조정하는 방법 | [Niels Rogge](https://github.com/nielsrogge) |[](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_PyTorch_Lightning.ipynb) |
+| [🤗 Trainer를 사용하여 CIFAR-10에서 비전 트랜스포머 미세 조정하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_the_%F0%9F%A4%97_Trainer.ipynb) | Datasets, 🤗 Trainer를 사용하여 CIFAR-10에서 비전 트랜스포머(ViT)를 미세 조정하는 방법 | [Niels Rogge](https://github.com/nielsrogge) |[](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_the_%F0%9F%A4%97_Trainer.ipynb) |
+| [개체 입력 데이터 세트인 Open Entity로 LUKE 평가하기](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_open_entity.ipynb) | Open Entity 데이터 세트로 *LukeForEntityClassification*을 평가하는 방법 | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_open_entity.ipynb) |
+| [관계 추출 데이터 세트인 TACRED로 LUKE 평가하기](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_tacred.ipynb) | TACRED 데이터 세트로 *LukeForEntityPairClassification*을 평가하는 방법 | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_tacred.ipynb) |
+| [중요 NER 벤치마크인 CoNLL-2003으로 LUKE 평가하기](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_conll_2003.ipynb) | CoNLL-2003 데이터 세트로 *LukeForEntitySpanClassification*를 평가하는 방법 | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_conll_2003.ipynb) |
+| [PubMed 데이터 세트로 BigBird-Pegasus 평가하기](https://github.com/vasudevgupta7/bigbird/blob/main/notebooks/bigbird_pegasus_evaluation.ipynb) | PubMed 데이터 세트로 *BigBirdPegasusForConditionalGeneration*를 평가하는 방법 | [Vasudev Gupta](https://github.com/vasudevgupta7) | [](https://colab.research.google.com/github/vasudevgupta7/bigbird/blob/main/notebooks/bigbird_pegasus_evaluation.ipynb) |
+| [Wav2Vec2를 사용해서 음성 감정 분류하기](https://github/m3hrdadfi/soxan/blob/main/notebooks/Emotion_recognition_in_Greek_speech_using_Wav2Vec2.ipynb) | 감정 분류를 위해 사전훈련된 Wav2Vec2 모델을 MEGA 데이터 세트에 활용하는 방법 | [Mehrdad Farahani](https://github.com/m3hrdadfi) | [](https://colab.research.google.com/github/m3hrdadfi/soxan/blob/main/notebooks/Emotion_recognition_in_Greek_speech_using_Wav2Vec2.ipynb) |
+| [DETR로 이미지에서 객체 탐지하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/DETR/DETR_minimal_example_(with_DetrFeatureExtractor).ipynb) | 훈련된 *DetrForObjectDetection* 모델을 사용하여 이미지에서 객체를 탐지하고 어텐션을 시각화하는 방법 | [Niels Rogge](https://github.com/NielsRogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/DETR/DETR_minimal_example_(with_DetrFeatureExtractor).ipynb) |
+| [사용자 지정 객체 탐지 데이터 세트로 DETR 미세 조정하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/DETR/Fine_tuning_DetrForObjectDetection_on_custom_dataset_(balloon).ipynb) | 사용자 지정 객체 탐지 데이터 세트로 *DetrForObjectDetection*을 미세 조정하는 방법 | [Niels Rogge](https://github.com/NielsRogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/DETR/Fine_tuning_DetrForObjectDetection_on_custom_dataset_(balloon).ipynb) |
+| [개체명 인식을 위해 T5 미세 조정하기](https://github.com/ToluClassics/Notebooks/blob/main/T5_Ner_Finetuning.ipynb) | 개체명 인식 작업을 위해 *T5*를 미세 조정하는 방법 | [Ogundepo Odunayo](https://github.com/ToluClassics) | [](https://colab.research.google.com/drive/1obr78FY_cBmWY5ODViCmzdY6O1KB65Vc?usp=sharing) |
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/contributing.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/contributing.md
new file mode 100644
index 0000000000000000000000000000000000000000..99f1d2b66647285d9f2517949be149da2c1ae931
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/contributing.md
@@ -0,0 +1,332 @@
+
+
+# 🤗 Transformers에 기여하기 [[contribute-to-transformers]]
+
+누구나 🤗 Transformers에 기여할 수 있으며, 우리는 모든 사람의 기여를 소중히 생각합니다. 코드 기여는 커뮤니티를 돕는 유일한 방법이 아닙니다. 질문에 답하거나 다른 사람을 도와 문서를 개선하는 것도 매우 가치가 있습니다.
+
+🤗 Transformers를 널리 알리는 것도 큰 도움이 됩니다! 멋진 프로젝트들을 가능하게 한 🤗 Transformers 라이브러리에 대해 블로그 게시글에 언급하거나, 도움이 되었을 때마다 Twitter에 알리거나, 저장소에 ⭐️ 를 표시하여 감사 인사를 전해주세요.
+
+어떤 방식으로 기여하든 [행동 규칙](https://github.com/huggingface/transformers/blob/main/CODE_OF_CONDUCT.md)을 숙지하고 존중해주세요.
+
+**이 안내서는 멋진 [scikit-learn 기여 안내서](https://github.com/scikit-learn/scikit-learn/blob/main/CONTRIBUTING.md)에서 큰 영감을 받았습니다.**
+
+## 기여하는 방법 [[ways-to-contribute]]
+
+여러 가지 방법으로 🤗 Transformers에 기여할 수 있습니다:
+
+* 기존 코드의 미해결된 문제를 수정합니다.
+* 버그 또는 새로 추가되길 원하는 기능과 관련된 이슈를 제출합니다.
+* 새로운 모델을 구현합니다.
+* 예제나 문서에 기여합니다.
+
+어디서부터 시작할지 모르겠다면, [Good First Issue](https://github.com/huggingface/transformers/contribute) 목록을 확인해보세요. 이 목록은 초보자도 참여하기 쉬운 오픈 이슈 목록을 제공하며, 당신이 오픈소스에 처음으로 기여하는 데 큰 도움이 될 것입니다. 그저 작업하고 싶은 이슈에 댓글만 달아주면 됩니다.
+
+조금 더 도전적인 작업을 원한다면, [Good Second Issue](https://github.com/huggingface/transformers/labels/Good%20Second%20Issue) 목록도 확인해보세요. 이미 당신이 잘 하고 있다고 생각되더라도, 한 번 시도해보세요! 우리도 여러분을 도울 것입니다. 🚀
+
+> 커뮤니티에 이루어지는 모든 기여는 똑같이 소중합니다. 🥰
+
+## 미해결된 문제 수정하기 [[fixing-outstanding-issues]]
+
+기존 코드에서 발견한 문제점에 대한 해결책이 떠오른 경우, 언제든지 [기여를 시작](https://github.com/huggingface/transformers/blob/main/CONTRIBUTING.md/#create-a-pull-request)하고 Pull Request를 생성해주세요!
+
+## 버그 관련 이슈를 제기하거나 새로운 기능 요청하기 [[submitting-a-bugrelated-issue-or-feature-request]]
+
+버그 관련 이슈를 제기하거나 새로운 기능을 요청할 때는 다음 가이드라인을 최대한 준수해주세요. 이렇게 하면 좋은 피드백과 함께 빠르게 답변해 드릴 수 있습니다.
+
+### 버그를 발견하셨나요? [[did-you-find-a-bug]]
+
+🤗 Transformers 라이브러리는 사용 중에 겪는 문제를 보고해주는 사용자들 덕분에 더욱 견고해지고 신뢰할 수 있게 되었습니다.
+
+이슈를 보고하기 전에, 버그가 이미 **보고되지 않았는지** 확인해주세요. (GitHub의 이슈 탭 아래의 검색 바를 사용하세요). 이슈는 라이브러리 자체에서 발생한 버그어야 하며, 코드의 다른 부분과 관련된 것이 아니어야 합니다. 버그가 라이브러리의 문제로 발생하였는지 확실하지 않은 경우 먼저 [포럼](https://discuss.huggingface.co/)에서 질문해 주세요. 이렇게 하면 일반적인 질문보다 라이브러리와 관련된 문제를 더 빠르게 해결할 수 있습니다.
+
+버그가 이미 보고되지 않았다는 것을 확인했다면, 다음 정보를 포함하여 이슈를 제출해 주세요. 그러면 우리가 빠르게 해결할 수 있습니다:
+
+* 사용 중인 **운영체제 종류와 버전**, 그리고 **Python**, **PyTorch** 또는 **TensorFlow** 버전.
+* 버그를 30초 이내로 재현할 수 있는 간단하고 독립적인 코드 스니펫.
+* 예외가 발생한 경우 *전체* 트레이스백.
+* 스크린샷과 같이 도움이 될 것으로 생각되는 추가 정보를 첨부해 주세요.
+
+운영체제와 소프트웨어 버전을 자동으로 가져오려면 다음 명령을 실행하세요:
+
+```bash
+transformers-cli env
+```
+
+저장소의 루트 디렉터리에서도 같은 명령을 실행할 수 있습니다:
+
+```bash
+python src/transformers/commands/transformers_cli.py env
+```
+
+
+### 새로운 기능을 원하시나요? [[do-you-want-a-new-feature]]
+
+🤗 Transformers에서 사용하고 싶은 새로운 기능이 있다면, 다음 내용을 포함하여 이슈를 제출해 주세요:
+
+1. 이 기능이 필요한 *이유*는 무엇인가요? 라이브러리에 대한 문제나 불만과 관련이 있나요? 프로젝트에 필요한 기능인가요? 커뮤니티에 도움이 될 만한 기능인가요?
+
+ 어떤 내용이든 여러분의 이야기를 듣고 싶습니다!
+
+2. 요청하는 기능을 최대한 자세히 설명해 주세요. 더 많은 정보를 제공할수록 더 나은 도움을 드릴 수 있습니다.
+3. 해당 기능의 사용법을 보여주는 *코드 스니펫*을 제공해 주세요.
+4. 기능과 관련된 논문이 있는 경우 링크를 포함해 주세요.
+
+이슈가 잘 작성되었다면 이슈가 생성된 순간, 이미 80% 정도의 작업이 완료된 것입니다.
+
+이슈를 제기하는 데 도움이 될 만한 [템플릿](https://github.com/huggingface/transformers/tree/main/templates)도 준비되어 있습니다.
+
+## 새로운 모델을 구현하고 싶으신가요? [[do-you-want-to-implement-a-new-model]]
+
+새로운 모델은 계속해서 출시됩니다. 만약 여러분이 새로운 모델을 구현하고 싶다면 다음 정보를 제공해 주세요:
+
+* 모델에 대한 간단한 설명과 논문 링크.
+* 구현이 공개되어 있다면 구현 링크.
+* 모델 가중치가 사용 가능하다면 가중치 링크.
+
+만약 모델을 직접 기여하고 싶으시다면, 알려주세요. 🤗 Transformers에 추가할 수 있도록 도와드리겠습니다!
+
+[🤗 Transformers에 새로운 모델을 추가하는 방법](https://huggingface.co/docs/transformers/add_new_model)에 대한 기술적인 안내서도 있습니다.
+
+## 문서를 추가하고 싶으신가요? [[do-you-want-to-add-documentation]]
+
+우리는 언제나 더 명확하고 정확한 문서를 제공하기 위하여 개선점을 찾고 있습니다. 오탈자나 부족한 내용, 분명하지 않거나 부정확한 내용 등을 알려주시면 개선하는 데 도움이 됩니다. 관심이 있으시다면 변경하거나 기여하실 수 있도록 도와드리겠습니다!
+
+문서를 생성, 빌드 및 작성하는 방법에 대한 자세한 내용은 [README](https://github.com/huggingface/transformers/tree/main/docs) 문서를 확인해 주세요.
+
+## 풀 리퀘스트(Pull Request) 생성하기 [[create-a-pull-request]]
+
+코드를 작성하기 전에 기존의 Pull Request나 이슈를 검색하여 누군가 이미 동일한 작업을 하고 있는지 확인하는 것이 좋습니다. 확실하지 않다면 피드백을 받기 위해 이슈를 열어보는 것이 좋습니다.
+
+🤗 Transformers에 기여하기 위해서는 기본적인 `git` 사용 능력이 필요합니다. `git`은 사용하기 쉬운 도구는 아니지만, 매우 훌륭한 매뉴얼을 제공합니다. 쉘(shell)에서 `git --help`을 입력하여 확인해보세요! 만약 책을 선호한다면, [Pro Git](https://git-scm.com/book/en/v2)은 매우 좋은 참고 자료가 될 것입니다.
+
+🤗 Transformers에 기여하려면 **[Python 3.9](https://github.com/huggingface/transformers/blob/main/setup.py#L426)** 이상의 버전이 필요합니다. 기여를 시작하려면 다음 단계를 따르세요:
+
+1. 저장소 페이지에서 **[Fork](https://github.com/huggingface/transformers/fork)** 버튼을 클릭하여 저장소를 포크하세요. 이렇게 하면 코드의 복사본이 여러분의 GitHub 사용자 계정 아래에 생성됩니다.
+
+2. 포크한 저장소를 로컬 디스크로 클론하고, 기본 저장소를 원격(remote)으로 추가하세요:
+
+ ```bash
+ git clone git@github.com:/transformers.git
+ cd transformers
+ git remote add upstream https://github.com/huggingface/transformers.git
+ ```
+
+3. 개발 변경 사항을 저장할 새 브랜치를 생성하세요:
+
+ ```bash
+ git checkout -b a-descriptive-name-for-my-changes
+ ```
+
+ 🚨 절대 `main` 브랜치에서 작업하지 **마세요!**
+
+4. 가상 환경에서 다음 명령을 실행하여 개발 환경을 설정하세요:
+
+ ```bash
+ pip install -e ".[dev]"
+ ```
+
+ 만약 이미 가상 환경에 🤗 Transformers가 설치되어 있다면, `-e` 플래그를 사용하여 설치하기 전에 `pip uninstall transformers`로 제거해주세요.
+
+ 여러분의 운영체제에 따라서, 그리고 🤗 Transformers의 선택적 의존성의 수가 증가하면서, 이 명령이 실패할 수도 있습니다. 그럴 경우 사용하려는 딥러닝 프레임워크(PyTorch, TensorFlow, 그리고/또는 Flax)를 설치한 후 아래 명령을 실행해주세요:
+
+ ```bash
+ pip install -e ".[quality]"
+ ```
+
+ 대부분의 경우 이것으로 충분할 것입니다.
+
+5. 브랜치에서 기능을 개발하세요.
+
+ 코드를 작업하는 동안 테스트 스위트(test suite)가 통과하는지 확인하세요. 다음과 같이 변경 사항에 영향을 받는 테스트를 실행하세요:
+
+ ```bash
+ pytest tests/.py
+ ```
+
+ 테스트에 대한 더 많은 정보는 [테스트](https://huggingface.co/docs/transformers/testing) 가이드를 확인하세요.
+
+ 🤗 Transformers는 `black`과 `ruff`를 사용하여 소스 코드의 형식을 일관되게 유지합니다. 변경 사항을 적용한 후에는 다음 명령으로 자동으로 스타일 교정 및 코드 검증을 수행하세요:
+
+ ```bash
+ make fixup
+ ```
+
+ 이것은 또한 작업 중인 PR에서 수정한 파일에서만 작동하도록 최적화되어 있습니다.
+
+ 검사를 하나씩 실행하려는 경우, 다음 명령으로 스타일 교정을 적용할 수 있습니다:
+
+ ```bash
+ make style
+ ```
+
+ 🤗 Transformers는 또한 `ruff`와 몇 가지 사용자 정의 스크립트를 사용하여 코딩 실수를 확인합니다. CI를 통해 품질 관리가 수행되지만, 다음 명령으로 동일한 검사를 실행할 수 있습니다:
+
+ ```bash
+ make quality
+ ```
+
+ 마지막으로, 새 모델을 추가할 때 일부 파일을 업데이트하는 것을 잊지 않도록 하기 위한 많은 스크립트가 있습니다. 다음 명령으로 이러한 스크립트를 실행할 수 있습니다:
+
+ ```bash
+ make repo-consistency
+ ```
+
+ 이러한 검사에 대해 자세히 알아보고 관련 문제를 해결하는 방법은 [Pull Request에 대한 검사](https://huggingface.co/docs/transformers/pr_checks) 가이드를 확인하세요.
+
+ 만약 `docs/source` 디렉터리 아래의 문서를 수정하는 경우, 문서가 빌드될 수 있는지 확인하세요. 이 검사는 Pull Request를 열 때도 CI에서 실행됩니다. 로컬 검사를 실행하려면 문서 빌더를 설치해야 합니다:
+
+ ```bash
+ pip install ".[docs]"
+ ```
+
+ 저장소의 루트 디렉터리에서 다음 명령을 실행하세요:
+
+ ```bash
+ doc-builder build transformers docs/source/en --build_dir ~/tmp/test-build
+ ```
+
+ 이 명령은 `~/tmp/test-build` 폴더에 문서를 빌드하며, 생성된 Markdown 파일을 선호하는 편집기로 확인할 수 있습니다. Pull Request를 열 때 GitHub에서 문서를 미리 볼 수도 있습니다.
+
+ 변경 사항에 만족하면 `git add`로 변경된 파일을 추가하고, `git commit`으로 변경 사항을 로컬에 기록하세요:
+
+ ```bash
+ git add modified_file.py
+ git commit
+ ```
+
+ [좋은 커밋 메시지](https://chris.beams.io/posts/git-commit/)를 작성하여 변경 사항을 명확하게 전달하세요!
+
+ 변경 사항을 프로젝트 원본 저장소와 동기화하려면, PR을 *열기 전에* 브랜치를 `upstream/branch`로 리베이스(rebase)하세요. 또는 관리자의 요청에 이 작업이 필요할 수 있습니다:
+
+ ```bash
+ git fetch upstream
+ git rebase upstream/main
+ ```
+
+ 변경 사항을 브랜치에 푸시하세요:
+
+ ```bash
+ git push -u origin a-descriptive-name-for-my-changes
+ ```
+
+ 이미 PR을 열었다면, `--force` 플래그와 함께 강제 푸시해야 합니다. 아직 PR이 열리지 않았다면 정상적으로 변경 사항을 푸시하면 됩니다.
+
+6. 이제 GitHub에서 포크한 저장소로 이동하고 **Pull request(풀 리퀘스트)**를 클릭하여 Pull Request를 열 수 있습니다. 아래의 [체크리스트](https://github.com/huggingface/transformers/blob/main/CONTRIBUTING.md/#pull-request-checklist)에서 모든 항목에 체크 표시를 하세요. 준비가 완료되면 프로젝트 관리자에게 변경 사항을 보내 검토를 요청할 수 있습니다.
+
+7. 관리자가 변경 사항을 요청해도 괜찮습니다. 핵심 기여자들도 동일한 상황을 겪습니다! 모두가 변경 사항을 Pull Request에서 볼 수 있도록, 로컬 브랜치에서 작업하고 변경 사항을 포크한 저장소로 푸시하세요. 그러면 변경 사항이 자동으로 Pull Request에 나타납니다.
+
+### Pull Request 체크리스트 [[pull-request-checklist]]
+
+☐ Pull Request 제목은 기여 내용을 요약해야 합니다.
+
+테스트를 실행하려면 *하위 폴더 경로 또는 테스트 파일 경로*를 지정하세요. 그렇지 않으면 `tests` 또는 `examples` 폴더의 모든 테스트를 실행하게 되어 매우 긴 시간이 걸립니다!
+
+
+
+```bash
+RUN_SLOW=yes python -m pytest -n auto --dist=loadfile -s -v ./tests/models/my_new_model
+RUN_SLOW=yes python -m pytest -n auto --dist=loadfile -s -v ./examples/pytorch/text-classification
+```
+
+느린 테스트와 마찬가지로, 다음과 같이 테스트 중에 기본적으로 활성화되지 않는 다른 환경 변수도 있습니다:
+- `RUN_CUSTOM_TOKENIZERS`: 사용자 정의 토크나이저 테스트를 활성화합니다.
+- `RUN_PT_FLAX_CROSS_TESTS`: PyTorch + Flax 통합 테스트를 활성화합니다.
+- `RUN_PT_TF_CROSS_TESTS`: TensorFlow + PyTorch 통합 테스트를 활성화합니다.
+
+더 많은 환경 변수와 추가 정보는 [testing_utils.py](src/transformers/testing_utils.py)에서 찾을 수 있습니다.
+
+🤗 Transformers는 테스트 실행기로 `pytest`를 사용합니다. 그러나 테스트 스위트 자체에서는 `pytest` 관련 기능을 사용하지 않습니다.
+
+이것은 `unittest`가 완전히 지원된다는 것을 의미합니다. 다음은 `unittest`로 테스트를 실행하는 방법입니다:
+
+```bash
+python -m unittest discover -s tests -t . -v
+python -m unittest discover -s examples -t examples -v
+```
+
+### 스타일 가이드 [[style-guide]]
+
+문서는 [Google Python 스타일 가이드](https://google.github.io/styleguide/pyguide.html)를 따릅니다. 자세한 정보는 [문서 작성 가이드](https://github.com/huggingface/transformers/tree/main/docs#writing-documentation---specification)를 확인하세요.
+
+### Windows에서 개발 [[develop-on-windows]]
+
+Windows에서 개발할 경우([Windows Subsystem for Linux](https://learn.microsoft.com/en-us/windows/wsl/) 또는 WSL에서 작업하지 않는 한) Windows `CRLF` 줄 바꿈을 Linux `LF` 줄 바꿈으로 변환하도록 git을 구성해야 합니다:
+
+```bash
+git config core.autocrlf input
+```
+
+Windows에서 `make` 명령을 실행하는 한 가지 방법은 MSYS2를 사용하는 것입니다:
+
+1. [MSYS2](https://www.msys2.org/)를 다운로드합니다. `C:\msys64`에 설치되었다고 가정합니다.
+2. CLI에서 `C:\msys64\msys2.exe`를 엽니다 (시작 메뉴에서 사용 가능해야 함).
+3. 쉘에서 다음을 실행하여: `pacman -Syu` 및 `pacman -S make`로 `make`를 설치합니다.
+4. 환경 변수 PATH에 `C:\msys64\usr\bin`을 추가하세요.
+
+이제 모든 터미널 (PowerShell, cmd.exe 등)에서 `make`를 사용할 수 있습니다! 🎉
+
+### 포크한 저장소를 상위 원본 브랜치(main)과 동기화하기 (Hugging Face 저장소) [[sync-a-forked-repository-with-upstream-main-the-hugging-face-repository]]
+
+포크한 저장소의 main 브랜치를 업데이트할 때, 다음 단계를 따라 수행해주세요. 이렇게 하면 각 upstream PR에 참조 노트가 추가되는 것을 피하고 이러한 PR에 관여하는 개발자들에게 불필요한 알림이 전송되는 것을 방지할 수 있습니다.
+
+1. 가능하면 포크된 저장소의 브랜치 및 PR을 사용하여 upstream과 동기화하지 마세요. 대신 포크된 main 저장소에 직접 병합하세요.
+2. PR이 반드시 필요한 경우, 브랜치를 확인한 후 다음 단계를 사용하세요:
+
+ ```bash
+ git checkout -b your-branch-for-syncing
+ git pull --squash --no-commit upstream main
+ git commit -m ''
+ git push --set-upstream origin your-branch-for-syncing
+ ```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/conversations.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/conversations.md
new file mode 100644
index 0000000000000000000000000000000000000000..920cb1387860865e6f01ff47b79c50a2e9c4bea3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/conversations.md
@@ -0,0 +1,306 @@
+
+
+# Transformers로 채팅하기[[chatting-with-transformers]]
+
+이 글을 보고 있다면 **채팅 모델**에 대해 어느 정도 알고 계실 것입니다.
+채팅 모델이란 메세지를 주고받을 수 있는 대화형 인공지능입니다.
+대표적으로 ChatGPT가 있고, 이와 비슷하거나 더 뛰어난 오픈소스 채팅 모델이 많이 존재합니다.
+이러한 모델들은 무료 다운로드할 수 있으며, 로컬에서 실행할 수 있습니다.
+크고 무거운 모델은 고성능 하드웨어와 메모리가 필요하지만,
+저사양 GPU 혹은 일반 데스크탑이나 노트북 CPU에서도 잘 작동하는 소형 모델들도 있습니다.
+
+이 가이드는 채팅 모델을 처음 사용하는 분들에게 유용할 것입니다.
+우리는 간편한 고수준(High-Level) "pipeline"을 통해 빠른 시작 가이드를 진행할 것입니다.
+가이드에는 채팅 모델을 바로 시작할 때 필요한 모든 정보가 담겨 있습니다.
+빠른 시작 가이드 이후에는 채팅 모델이 정확히 무엇인지, 적절한 모델을 선택하는 방법과,
+채팅 모델을 사용하는 각 단계의 저수준(Low-Level) 분석 등 더 자세한 정보를 다룰 것입니다.
+또한 채팅 모델의 성능과 메모리 사용을 최적화하는 방법에 대한 팁도 제공할 것입니다.
+
+
+## 빠른 시작[[quickstart]]
+
+자세히 볼 여유가 없는 분들을 위해 간단히 요약해 보겠습니다:
+채팅 모델은 대화 메세지를 계속해서 생성해 나갑니다.
+즉, 짤막한 채팅 메세지를 모델에게 전달하면, 모델은 이를 바탕으로 응답을 추가하며 대화를 이어 나갑니다.
+이제 실제로 어떻게 작동하는지 살펴보겠습니다.
+먼저, 채팅을 만들어 보겠습니다:
+
+
+```python
+chat = [
+ {"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."},
+ {"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"}
+]
+```
+
+주목하세요, 대화를 처음 시작할 때 유저 메세지 이외의도, 별도의 **시스템** 메세지가 필요할 수 있습니다.
+모든 채팅 모델이 시스템 메세지를 지원하는 것은 아니지만,
+지원하는 경우에는 시스템 메세지는 대화에서 모델이 어떻게 행동해야 하는지를 지시할 수 있습니다.
+예를 들어, 유쾌하거나 진지하고자 할 때, 짧은 답변이나 긴 답변을 원할 때 등을 설정할 수 있습니다.
+시스템 메세지를 생략하고
+"You are a helpful and intelligent AI assistant who responds to user queries."
+와 같은 간단한 프롬프트를 사용하는 것도 가능합니다.
+
+채팅을 시작했다면 대화를 이어 나가는 가장 빠른 방법은 [`TextGenerationPipeline`]를 사용하는 것입니다.
+한번 `LLaMA-3`를 사용하여 이를 시연해 보겠습니다.
+우선 `LLaMA-3`를 사용하기 위해서는 승인이 필요합니다. [권한 신청](https://huggingface.co/meta-llama/Meta-Llama-3-8B-Instruct)을 하고 Hugging Face 계정으로 로그인한 후에 사용할 수 있습니다.
+또한 우리는 `device_map="auto"`를 사용합니다. GPU 메모리가 충분하다면 로드될 것입니다.
+그리고 메모리 절약을 위해 dtype을 `torch.bfloat16`으로 설정할 것입니다.
+
+```python
+import torch
+from transformers import pipeline
+
+pipe = pipeline("text-generation", "meta-llama/Meta-Llama-3-8B-Instruct", torch_dtype=torch.bfloat16, device_map="auto")
+response = pipe(chat, max_new_tokens=512)
+print(response[0]['generated_text'][-1]['content'])
+```
+
+이후 실행을 하면 아래와 같이 출력됩니다:
+
+```text
+(sigh) Oh boy, you're asking me for advice? You're gonna need a map, pal! Alright,
+alright, I'll give you the lowdown. But don't say I didn't warn you, I'm a robot, not a tour guide!
+
+So, you wanna know what's fun to do in the Big Apple? Well, let me tell you, there's a million
+things to do, but I'll give you the highlights. First off, you gotta see the sights: the Statue of
+Liberty, Central Park, Times Square... you know, the usual tourist traps. But if you're lookin' for
+something a little more... unusual, I'd recommend checkin' out the Museum of Modern Art. It's got
+some wild stuff, like that Warhol guy's soup cans and all that jazz.
+
+And if you're feelin' adventurous, take a walk across the Brooklyn Bridge. Just watch out for
+those pesky pigeons, they're like little feathered thieves! (laughs) Get it? Thieves? Ah, never mind.
+
+Now, if you're lookin' for some serious fun, hit up the comedy clubs in Greenwich Village. You might
+even catch a glimpse of some up-and-coming comedians... or a bunch of wannabes tryin' to make it big. (winks)
+
+And finally, if you're feelin' like a real New Yorker, grab a slice of pizza from one of the many amazing
+pizzerias around the city. Just don't try to order a "robot-sized" slice, trust me, it won't end well. (laughs)
+
+So, there you have it, pal! That's my expert advice on what to do in New York. Now, if you'll
+excuse me, I've got some oil changes to attend to. (winks)
+```
+
+채팅을 계속하려면, 자신의 답장을 추가하면 됩니다.
+파이프라인에서 반환된 `response` 객체에는 현재까지 모든 채팅을 포함하고 있으므로
+메세지를 추가하고 다시 전달하기만 하면 됩니다.
+
+```python
+chat = response[0]['generated_text']
+chat.append(
+ {"role": "user", "content": "Wait, what's so wild about soup cans?"}
+)
+response = pipe(chat, max_new_tokens=512)
+print(response[0]['generated_text'][-1]['content'])
+```
+
+이후 실행을 하면 아래와 같이 출력됩니다:
+
+```text
+(laughs) Oh, you're killin' me, pal! You don't get it, do you? Warhol's soup cans are like, art, man!
+It's like, he took something totally mundane, like a can of soup, and turned it into a masterpiece. It's
+like, "Hey, look at me, I'm a can of soup, but I'm also a work of art!"
+(sarcastically) Oh, yeah, real original, Andy.
+
+But, you know, back in the '60s, it was like, a big deal. People were all about challenging the
+status quo, and Warhol was like, the king of that. He took the ordinary and made it extraordinary.
+And, let me tell you, it was like, a real game-changer. I mean, who would've thought that a can of soup could be art? (laughs)
+
+But, hey, you're not alone, pal. I mean, I'm a robot, and even I don't get it. (winks)
+But, hey, that's what makes art, art, right? (laughs)
+```
+
+이 튜토리얼의 후반부에서는 성능과 메모리 관리,
+그리고 사용자의 필요에 맞는 채팅 모델 선택과 같은 구체적인 주제들을 다룰 것입니다.
+
+## 채팅 모델 고르기[[choosing-a-chat-model]]
+
+[Hugging Face Hub](https://huggingface.co/models?pipeline_tag=text-generation&sort=trending)는 채팅 모델을 다양하게 제공하고 있습니다.
+처음 사용하는 사람에게는 모델을 선택하기가 어려울지 모릅니다.
+하지만 걱정하지 마세요! 두 가지만 명심하면 됩니다:
+
+- 모델의 크기는 실행 속도와 메모리에 올라올 수 있는지 여부를 결정.
+- 모델이 생성한 출력의 품질.
+
+일반적으로 이러한 요소들은 상관관계가 있습니다. 더 큰 모델일수록 더 뛰어난 성능을 보이는 경향이 있지만, 동일한 크기의 모델이라도 유의미한 차이가 날 수 있습니다!
+
+### 모델의 명칭과 크기[[size-and-model-naming]]
+
+모델의 크기는 모델 이름에 있는 숫자로 쉽게 알 수 있습니다.
+예를 들어, "8B" 또는 "70B"와 같은 숫자는 모델의 **파라미터** 수를 나타냅니다.
+양자화된 경우가 아니라면, 파라미터 하나당 약 2바이트의 메모리가 필요하다고 예상 가능합니다.
+따라서 80억 개의 파라미터를 가진 "8B" 모델은 16GB의 메모리를 차지하며, 추가적인 오버헤드를 위한 약간의 여유가 필요합니다.
+이는 3090이나 4090와 같은 24GB의 메모리를 갖춘 하이엔드 GPU에 적합합니다.
+
+일부 채팅 모델은 "Mixture of Experts" 모델입니다.
+이러한 모델은 크기를 "8x7B" 또는 "141B-A35B"와 같이 다르게 표시하곤 합니다.
+숫자가 다소 모호하다 느껴질 수 있지만, 첫 번째 경우에는 약 56억(8x7) 개의 파라미터가 있고,
+두 번째 경우에는 약 141억 개의 파라미터가 있다고 해석할 수 있습니다.
+
+양자화는 파라미터당 메모리 사용량을 8비트, 4비트, 또는 그 이하로 줄이는 데 사용됩니다.
+이 주제에 대해서는 아래의 [메모리 고려사항](#memory-considerations) 챕터에서 더 자세히 다룰 예정입니다.
+
+### 그렇다면 어떤 채팅 모델이 가장 좋을까요?[[but-which-chat-model-is-best]]
+모델의 크기 외에도 고려할 점이 많습니다.
+이를 한눈에 살펴보려면 **리더보드**를 참고하는 것이 좋습니다.
+가장 인기 있는 리더보드 두 가지는 [OpenLLM Leaderboard](https://huggingface.co/spaces/HuggingFaceH4/open_llm_leaderboard)와 [LMSys Chatbot Arena Leaderboard](https://chat.lmsys.org/?leaderboard)입니다.
+LMSys 리더보드에는 독점 모델도 포함되어 있으니,
+`license` 열에서 접근 가능한 모델을 선택한 후
+[Hugging Face Hub](https://huggingface.co/models?pipeline_tag=text-generation&sort=trending)에서 검색해 보세요.
+
+### 전문 분야[[specialist-domains]]
+일부 모델은 의료 또는 법률 텍스트와 같은 특정 도메인이나 비영어권 언어에 특화되어 있기도 합니다.
+이러한 도메인에서 작업할 경우 특화된 모델이 좋은 성능을 보일 수 있습니다.
+하지만 항상 그럴 것이라 단정하기는 힘듭니다.
+특히 모델의 크기가 작거나 오래된 모델인 경우,
+최신 범용 모델이 더 뛰어날 수 있습니다.
+다행히도 [domain-specific leaderboards](https://huggingface.co/blog/leaderboard-medicalllm)가 점차 등장하고 있어, 특정 도메인에 최고의 모델을 쉽게 찾을 수 있을 것입니다.
+
+
+## 파이프라인 내부는 어떻게 되어있는가?[[what-happens-inside-the-pipeline]]
+위의 빠른 시작에서는 고수준(High-Level) 파이프라인을 사용하였습니다.
+이는 간편한 방법이지만, 유연성은 떨어집니다.
+이제 더 저수준(Low-Level) 접근 방식을 통해 대화에 포함된 각 단계를 살펴보겠습니다.
+코드 샘플로 시작한 후 이를 분석해 보겠습니다:
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+import torch
+
+# 입력값을 사전에 준비해 놓습니다
+chat = [
+ {"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."},
+ {"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"}
+]
+
+# 1: 모델과 토크나이저를 불러옵니다
+model = AutoModelForCausalLM.from_pretrained("meta-llama/Meta-Llama-3-8B-Instruct", device_map="auto", torch_dtype=torch.bfloat16)
+tokenizer = AutoTokenizer.from_pretrained("meta-llama/Meta-Llama-3-8B-Instruct")
+
+# 2: 채팅 템플릿에 적용합니다
+formatted_chat = tokenizer.apply_chat_template(chat, tokenize=False, add_generation_prompt=True)
+print("Formatted chat:\n", formatted_chat)
+
+# 3: 채팅을 토큰화합니다 (바로 이전 과정에서 tokenized=True로 설정하면 한꺼번에 처리할 수 있습니다)
+inputs = tokenizer(formatted_chat, return_tensors="pt", add_special_tokens=False)
+# 토큰화된 입력값을 모델이 올라와 있는 기기(CPU/GPU)로 옮깁니다.
+inputs = {key: tensor.to(model.device) for key, tensor in inputs.items()}
+print("Tokenized inputs:\n", inputs)
+
+# 4: 모델로부터 응답을 생성합니다
+outputs = model.generate(**inputs, max_new_tokens=512, temperature=0.1)
+print("Generated tokens:\n", outputs)
+
+# 5: 모델이 출력한 토큰을 다시 문자열로 디코딩합니다
+decoded_output = tokenizer.decode(outputs[0][inputs['input_ids'].size(1):], skip_special_tokens=True)
+print("Decoded output:\n", decoded_output)
+```
+여기에는 각 부분이 자체 문서가 될 수 있을 만큼 많은 내용이 담겨 있습니다!
+너무 자세히 설명하기보다는 넓은 개념을 다루고, 세부 사항은 링크된 문서에서 다루겠습니다.
+주요 단계는 다음과 같습니다:
+
+1. [모델](https://huggingface.co/learn/nlp-course/en/chapter2/3)과 [토크나이저](https://huggingface.co/learn/nlp-course/en/chapter2/4?fw=pt)를 Hugging Face Hub에서 로드합니다.
+2. 대화는 토크나이저의 [채팅 템플릿](https://huggingface.co/docs/transformers/main/en/chat_templating)을 사용하여 양식을 구성합니다.
+3. 구성된 채팅은 토크나이저를 사용하여 [토큰화](https://huggingface.co/learn/nlp-course/en/chapter2/4)됩니다.
+4. 모델에서 응답을 [생성](https://huggingface.co/docs/transformers/en/llm_tutorial)합니다.
+5. 모델이 출력한 토큰을 다시 문자열로 디코딩합니다.
+
+## 성능, 메모리와 하드웨어[[performance-memory-and-hardware]]
+이제 대부분의 머신 러닝 작업이 GPU에서 실행된다는 것을 아실 겁니다.
+다소 느리기는 해도 CPU에서 채팅 모델이나 언어 모델로부터 텍스트를 생성하는 것도 가능합니다.
+하지만 모델을 GPU 메모리에 올려놓을 수만 있다면, GPU를 사용하는 것이 일반적으로 더 선호되는 방식입니다.
+
+### 메모리 고려사항[[memory-considerations]]
+
+기본적으로, [`TextGenerationPipeline`]이나 [`AutoModelForCausalLM`]과 같은
+Hugging Face 클래스는 모델을 `float32` 정밀도(Precision)로 로드합니다.
+이는 파라미터당 4바이트(32비트)를 필요로 하므로,
+80억 개의 파라미터를 가진 "8B" 모델은 약 32GB의 메모리를 필요로 한다는 것을 의미합니다.
+하지만 이는 낭비일 수 있습니다!
+대부분의 최신 언어 모델은 파라미터당 2바이트를 사용하는 "bfloat16" 정밀도(Precision)로 학습됩니다.
+하드웨어가 이를 지원하는 경우(Nvidia 30xx/Axxx 이상),
+`torch_dtype` 파라미터로 위와 같이 `bfloat16` 정밀도(Precision)로 모델을 로드할 수 있습니다.
+
+또한, 16비트보다 더 낮은 정밀도(Precision)로 모델을 압축하는
+"양자화(quantization)" 방법을 사용할 수도 있습니다.
+이 방법은 모델의 가중치를 손실 압축하여 각 파라미터를 8비트,
+4비트 또는 그 이하로 줄일 수 있습니다.
+특히 4비트에서 모델의 출력이 부정적인 영향을 받을 수 있지만,
+더 크고 강력한 채팅 모델을 메모리에 올리기 위해 이 같은 트레이드오프를 감수할 가치가 있습니다.
+이제 `bitsandbytes`를 사용하여 이를 실제로 확인해 보겠습니다:
+
+```python
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_8bit=True) # You can also try load_in_4bit
+model = AutoModelForCausalLM.from_pretrained("meta-llama/Meta-Llama-3-8B-Instruct", device_map="auto", quantization_config=quantization_config)
+```
+
+위의 작업은 `pipeline` API에도 적용 가능합니다:
+
+```python
+from transformers import pipeline, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_8bit=True) # You can also try load_in_4bit
+pipe = pipeline("text-generation", "meta-llama/Meta-Llama-3-8B-Instruct", device_map="auto", model_kwargs={"quantization_config": quantization_config})
+```
+
+`bitsandbytes` 외에도 모델을 양자화하는 다양한 방법이 있습니다.
+자세한 내용은 [Quantization guide](./quantization)를 참조해 주세요.
+
+
+### 성능 고려사항[[performance-considerations]]
+
+
+
+언어 모델 성능과 최적화에 대한 보다 자세한 가이드는 [LLM Inference Optimization](./llm_optims)을 참고하세요.
+
+
+
+
+일반적으로 더 큰 채팅 모델은 메모리를 더 많이 요구하고,
+속도도 느려지는 경향이 있습니다. 구체적으로 말하자면,
+채팅 모델에서 텍스트를 생성할 때는 컴퓨팅 파워보다 **메모리 대역폭**이 병목 현상을 일으키는 경우가 많습니다.
+이는 모델이 토큰을 하나씩 생성할 때마다 파라미터를 메모리에서 읽어야 하기 때문입니다.
+따라서 채팅 모델에서 초당 생성할 수 있는 토큰 수는 모델이 위치한 메모리의 대역폭을 모델의 크기로 나눈 값에 비례합니다.
+
+위의 예제에서는 모델이 bfloat16 정밀도(Precision)로 로드될 때 용량이 약 16GB였습니다.
+이 경우, 모델이 생성하는 각 토큰마다 16GB를 메모리에서 읽어야 한다는 의미입니다.
+총 메모리 대역폭은 소비자용 CPU에서는 20-100GB/sec,
+소비자용 GPU나 Intel Xeon, AMD Threadripper/Epyc,
+애플 실리콘과 같은 특수 CPU에서는 200-900GB/sec,
+데이터 센터 GPU인 Nvidia A100이나 H100에서는 최대 2-3TB/sec에 이를 수 있습니다.
+이러한 정보는 각자 하드웨어에서 생성 속도를 예상하는 데 도움이 될 것입니다.
+
+따라서 텍스트 생성 속도를 개선하려면 가장 간단한 방법은 모델의 크기를 줄이거나(주로 양자화를 사용),
+메모리 대역폭이 더 높은 하드웨어를 사용하는 것입니다.
+이 대역폭 병목 현상을 피할 수 있는 고급 기술도 여러 가지 있습니다.
+가장 일반적인 방법은 [보조 생성](https://huggingface.co/blog/assisted-generation), "추측 샘플링"이라고 불리는 기술입니다.
+이 기술은 종종 더 작은 "초안 모델"을 사용하여 여러 개의 미래 토큰을 한 번에 추측한 후,
+채팅 모델로 생성 결과를 확인합니다.
+만약 채팅 모델이 추측을 확인하면, 한 번의 순전파에서 여러 개의 토큰을 생성할 수 있어
+병목 현상이 크게 줄어들고 생성 속도가 빨라집니다.
+
+마지막으로, "Mixture of Experts" (MoE) 모델에 대해서도 짚고 넘어가 보도록 합니다.
+Mixtral, Qwen-MoE, DBRX와 같은 인기 있는 채팅 모델이 바로 MoE 모델입니다.
+이 모델들은 토큰을 생성할 때 모든 파라미터가 사용되지 않습니다.
+이로 인해 MoE 모델은 전체 크기가 상당히 클 수 있지만,
+차지하는 메모리 대역폭은 낮은 편입니다.
+따라서 동일한 크기의 일반 "조밀한(Dense)" 모델보다 몇 배 빠를 수 있습니다.
+하지만 보조 생성과 같은 기술은 MoE 모델에서 비효율적일 수 있습니다.
+새로운 추측된 토큰이 추가되면서 더 많은 파라미터가 활성화되기 때문에,
+MoE 아키텍처가 제공하는 속도 이점이 상쇄될 수 있습니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/create_a_model.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/create_a_model.md
new file mode 100644
index 0000000000000000000000000000000000000000..b911669bb174b96ac8b43c9c9490bc16b75f3a7e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/create_a_model.md
@@ -0,0 +1,388 @@
+
+
+# 맞춤형 아키텍처 만들기[[create-a-custom-architecture]]
+
+[`AutoClass`](model_doc/auto)는 모델 아키텍처를 자동으로 추론하고 미리 학습된 configuration과 가중치를 다운로드합니다. 일반적으로 체크포인트에 구애받지 않는 코드를 생성하려면 `AutoClass`를 사용하는 것이 좋습니다. 하지만 특정 모델 파라미터를 보다 세밀하게 제어하고자 하는 사용자는 몇 가지 기본 클래스만으로 커스텀 🤗 Transformers 모델을 생성할 수 있습니다. 이는 🤗 Transformers 모델을 연구, 교육 또는 실험하는 데 관심이 있는 모든 사용자에게 특히 유용할 수 있습니다. 이 가이드에서는 'AutoClass'를 사용하지 않고 커스텀 모델을 만드는 방법에 대해 알아보겠습니다:
+
+- 모델 configuration을 가져오고 사용자 지정합니다.
+- 모델 아키텍처를 생성합니다.
+- 텍스트에 사용할 느리거나 빠른 토큰화기를 만듭니다.
+- 비전 작업을 위한 이미지 프로세서를 생성합니다.
+- 오디오 작업을 위한 특성 추출기를 생성합니다.
+- 멀티모달 작업용 프로세서를 생성합니다.
+
+## Configuration[[configuration]]
+
+[configuration](main_classes/configuration)은 모델의 특정 속성을 나타냅니다. 각 모델 구성에는 서로 다른 속성이 있습니다. 예를 들어, 모든 NLP 모델에는 `hidden_size`, `num_attention_heads`, `num_hidden_layers` 및 `vocab_size` 속성이 공통으로 있습니다. 이러한 속성은 모델을 구성할 attention heads 또는 hidden layers의 수를 지정합니다.
+
+[DistilBERT](model_doc/distilbert) 속성을 검사하기 위해 [`DistilBertConfig`]에 접근하여 자세히 살펴봅니다:
+
+```py
+>>> from transformers import DistilBertConfig
+
+>>> config = DistilBertConfig()
+>>> print(config)
+DistilBertConfig {
+ "activation": "gelu",
+ "attention_dropout": 0.1,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+[`DistilBertConfig`]는 기본 [`DistilBertModel`]을 빌드하는 데 사용되는 모든 기본 속성을 표시합니다. 모든 속성은 커스터마이징이 가능하므로 실험을 위한 공간을 만들 수 있습니다. 예를 들어 기본 모델을 다음과 같이 커스터마이즈할 수 있습니다:
+
+- `activation` 파라미터로 다른 활성화 함수를 사용해 보세요.
+- `attention_dropout` 파라미터를 사용하여 어텐션 확률에 더 높은 드롭아웃 비율을 사용하세요.
+
+```py
+>>> my_config = DistilBertConfig(activation="relu", attention_dropout=0.4)
+>>> print(my_config)
+DistilBertConfig {
+ "activation": "relu",
+ "attention_dropout": 0.4,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+사전 학습된 모델 속성은 [`~PretrainedConfig.from_pretrained`] 함수에서 수정할 수 있습니다:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("distilbert/distilbert-base-uncased", activation="relu", attention_dropout=0.4)
+```
+
+모델 구성이 만족스러우면 [`~PretrainedConfig.save_pretrained`]로 저장할 수 있습니다. 설정 파일은 지정된 작업 경로에 JSON 파일로 저장됩니다:
+
+```py
+>>> my_config.save_pretrained(save_directory="./your_model_save_path")
+```
+
+configuration 파일을 재사용하려면 [`~PretrainedConfig.from_pretrained`]를 사용하여 가져오세요:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/config.json")
+```
+
+
+
+configuration 파일을 딕셔너리로 저장하거나 사용자 정의 configuration 속성과 기본 configuration 속성의 차이점만 저장할 수도 있습니다! 자세한 내용은 [configuration](main_classes/configuration) 문서를 참조하세요.
+
+
+
+## 모델[[model]]
+
+다음 단계는 [모델(model)](main_classes/models)을 만드는 것입니다. 느슨하게 아키텍처라고도 불리는 모델은 각 계층이 수행하는 동작과 발생하는 작업을 정의합니다. configuration의 `num_hidden_layers`와 같은 속성은 아키텍처를 정의하는 데 사용됩니다. 모든 모델은 기본 클래스 [`PreTrainedModel`]과 입력 임베딩 크기 조정 및 셀프 어텐션 헤드 가지 치기와 같은 몇 가지 일반적인 메소드를 공유합니다. 또한 모든 모델은 [`torch.nn.Module`](https://pytorch.org/docs/stable/generated/torch.nn.Module.html), [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) 또는 [`flax.linen.Module`](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html)의 서브클래스이기도 합니다. 즉, 모델은 각 프레임워크의 사용법과 호환됩니다.
+
+
+
+사용자 지정 configuration 속성을 모델에 가져옵니다:
+
+```py
+>>> from transformers import DistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/config.json")
+>>> model = DistilBertModel(my_config)
+```
+
+이제 사전 학습된 가중치 대신 임의의 값을 가진 모델이 생성됩니다. 이 모델을 훈련하기 전까지는 유용하게 사용할 수 없습니다. 훈련은 비용과 시간이 많이 소요되는 프로세스입니다. 일반적으로 훈련에 필요한 리소스의 일부만 사용하면서 더 나은 결과를 더 빨리 얻으려면 사전 훈련된 모델을 사용하는 것이 좋습니다.
+
+사전 학습된 모델을 [`~PreTrainedModel.from_pretrained`]로 생성합니다:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+🤗 Transformers에서 제공한 모델의 사전 학습된 가중치를 사용하는 경우 기본 모델 configuration을 자동으로 불러옵니다. 그러나 원하는 경우 기본 모델 configuration 속성의 일부 또는 전부를 사용자 지정으로 바꿀 수 있습니다:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+사용자 지정 configuration 속성을 모델에 불러옵니다:
+
+```py
+>>> from transformers import TFDistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+>>> tf_model = TFDistilBertModel(my_config)
+```
+
+이제 사전 학습된 가중치 대신 임의의 값을 가진 모델이 생성됩니다. 이 모델을 훈련하기 전까지는 유용하게 사용할 수 없습니다. 훈련은 비용과 시간이 많이 소요되는 프로세스입니다. 일반적으로 훈련에 필요한 리소스의 일부만 사용하면서 더 나은 결과를 더 빨리 얻으려면 사전 훈련된 모델을 사용하는 것이 좋습니다.
+
+사전 학습된 모델을 [`~TFPreTrainedModel.from_pretrained`]로 생성합니다:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+🤗 Transformers에서 제공한 모델의 사전 학습된 가중치를 사용하는 경우 기본 모델 configuration을 자동으로 불러옵니다. 그러나 원하는 경우 기본 모델 configuration 속성의 일부 또는 전부를 사용자 지정으로 바꿀 수 있습니다:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+
+### 모델 헤드[[model-heads]]
+
+이 시점에서 *은닉 상태(hidden state)*를 출력하는 기본 DistilBERT 모델을 갖게 됩니다. 은닉 상태는 최종 출력을 생성하기 위해 모델 헤드에 입력으로 전달됩니다. 🤗 Transformers는 모델이 해당 작업을 지원하는 한 각 작업마다 다른 모델 헤드를 제공합니다(즉, 번역과 같은 시퀀스 간 작업에는 DistilBERT를 사용할 수 없음).
+
+
+
+예를 들어, [`DistilBertForSequenceClassification`]은 시퀀스 분류 헤드가 있는 기본 DistilBERT 모델입니다. 시퀀스 분류 헤드는 풀링된 출력 위에 있는 선형 레이어입니다.
+
+```py
+>>> from transformers import DistilBertForSequenceClassification
+
+>>> model = DistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+다른 모델 헤드로 전환하여 이 체크포인트를 다른 작업에 쉽게 재사용할 수 있습니다. 질의응답 작업의 경우, [`DistilBertForQuestionAnswering`] 모델 헤드를 사용할 수 있습니다. 질의응답 헤드는 숨겨진 상태 출력 위에 선형 레이어가 있다는 점을 제외하면 시퀀스 분류 헤드와 유사합니다.
+
+```py
+>>> from transformers import DistilBertForQuestionAnswering
+
+>>> model = DistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+예를 들어, [`TFDistilBertForSequenceClassification`]은 시퀀스 분류 헤드가 있는 기본 DistilBERT 모델입니다. 시퀀스 분류 헤드는 풀링된 출력 위에 있는 선형 레이어입니다.
+
+```py
+>>> from transformers import TFDistilBertForSequenceClassification
+
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+다른 모델 헤드로 전환하여 이 체크포인트를 다른 작업에 쉽게 재사용할 수 있습니다. 질의응답 작업의 경우, [`TFDistilBertForQuestionAnswering`] 모델 헤드를 사용할 수 있습니다. 질의응답 헤드는 숨겨진 상태 출력 위에 선형 레이어가 있다는 점을 제외하면 시퀀스 분류 헤드와 유사합니다.
+
+```py
+>>> from transformers import TFDistilBertForQuestionAnswering
+
+>>> tf_model = TFDistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+## 토크나이저[[tokenizer]]
+
+텍스트 데이터에 모델을 사용하기 전에 마지막으로 필요한 기본 클래스는 원시 텍스트를 텐서로 변환하는 [토크나이저](main_classes/tokenizer)입니다. 🤗 Transformers에 사용할 수 있는 토크나이저는 두 가지 유형이 있습니다:
+
+- [`PreTrainedTokenizer`]: 파이썬으로 구현된 토크나이저입니다.
+- [`PreTrainedTokenizerFast`]: Rust 기반 [🤗 Tokenizer](https://huggingface.co/docs/tokenizers/python/latest/) 라이브러리로 만들어진 토크나이저입니다. 이 토크나이저는 Rust로 구현되어 배치 토큰화에서 특히 빠릅니다. 빠른 토크나이저는 토큰을 원래 단어나 문자에 매핑하는 *오프셋 매핑*과 같은 추가 메소드도 제공합니다.
+두 토크나이저 모두 인코딩 및 디코딩, 새 토큰 추가, 특수 토큰 관리와 같은 일반적인 방법을 지원합니다.
+
+
+
+모든 모델이 빠른 토크나이저를 지원하는 것은 아닙니다. 이 [표](index#supported-frameworks)에서 모델의 빠른 토크나이저 지원 여부를 확인하세요.
+
+
+
+토크나이저를 직접 학습한 경우, *어휘(vocabulary)* 파일에서 토크나이저를 만들 수 있습니다:
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> my_tokenizer = DistilBertTokenizer(vocab_file="my_vocab_file.txt", do_lower_case=False, padding_side="left")
+```
+
+사용자 지정 토크나이저의 어휘는 사전 학습된 모델의 토크나이저에서 생성된 어휘와 다를 수 있다는 점을 기억하는 것이 중요합니다. 사전 학습된 모델을 사용하는 경우 사전 학습된 모델의 어휘를 사용해야 하며, 그렇지 않으면 입력이 의미를 갖지 못합니다. [`DistilBertTokenizer`] 클래스를 사용하여 사전 학습된 모델의 어휘로 토크나이저를 생성합니다:
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> slow_tokenizer = DistilBertTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+[`DistilBertTokenizerFast`] 클래스로 빠른 토크나이저를 생성합니다:
+
+```py
+>>> from transformers import DistilBertTokenizerFast
+
+>>> fast_tokenizer = DistilBertTokenizerFast.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+[`AutoTokenizer`]는 기본적으로 빠른 토크나이저를 가져오려고 합니다. 이 동작을 비활성화하려면 `from_pretrained`에서 `use_fast=False`를 설정하면 됩니다.
+
+
+
+## 이미지 프로세서[[image-processor]]
+
+이미지 프로세서(image processor)는 비전 입력을 처리합니다. 기본 [`~image_processing_utils.ImageProcessingMixin`] 클래스에서 상속합니다.
+
+사용하려면 사용 중인 모델과 연결된 이미지 프로세서를 생성합니다. 예를 들어, 이미지 분류에 [ViT](model_doc/vit)를 사용하는 경우 기본 [`ViTImageProcessor`]를 생성합니다:
+
+```py
+>>> from transformers import ViTImageProcessor
+
+>>> vit_extractor = ViTImageProcessor()
+>>> print(vit_extractor)
+ViTImageProcessor {
+ "do_normalize": true,
+ "do_resize": true,
+ "feature_extractor_type": "ViTImageProcessor",
+ "image_mean": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": 2,
+ "size": 224
+}
+```
+
+
+
+사용자 지정을 원하지 않는 경우 `from_pretrained` 메소드를 사용하여 모델의 기본 이미지 프로세서 매개변수를 불러오면 됩니다.
+
+
+
+사용자 지정 이미지 프로세서를 생성하려면 [`ViTImageProcessor`] 파라미터를 수정합니다:
+
+```py
+>>> from transformers import ViTImageProcessor
+
+>>> my_vit_extractor = ViTImageProcessor(resample="PIL.Image.BOX", do_normalize=False, image_mean=[0.3, 0.3, 0.3])
+>>> print(my_vit_extractor)
+ViTImageProcessor {
+ "do_normalize": false,
+ "do_resize": true,
+ "feature_extractor_type": "ViTImageProcessor",
+ "image_mean": [
+ 0.3,
+ 0.3,
+ 0.3
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": "PIL.Image.BOX",
+ "size": 224
+}
+```
+
+## 특성 추출기[[feature-extractor]]
+
+특성 추출기(feature extractor)는 오디오 입력을 처리합니다. 기본 [`~feature_extraction_utils.FeatureExtractionMixin`] 클래스에서 상속되며, 오디오 입력을 처리하기 위해 [`SequenceFeatureExtractor`] 클래스에서 상속할 수도 있습니다.
+
+사용하려면 사용 중인 모델과 연결된 특성 추출기를 생성합니다. 예를 들어, 오디오 분류에 [Wav2Vec2](model_doc/wav2vec2)를 사용하는 경우 기본 [`Wav2Vec2FeatureExtractor`]를 생성합니다:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> w2v2_extractor = Wav2Vec2FeatureExtractor()
+>>> print(w2v2_extractor)
+Wav2Vec2FeatureExtractor {
+ "do_normalize": true,
+ "feature_extractor_type": "Wav2Vec2FeatureExtractor",
+ "feature_size": 1,
+ "padding_side": "right",
+ "padding_value": 0.0,
+ "return_attention_mask": false,
+ "sampling_rate": 16000
+}
+```
+
+
+
+사용자 지정이 필요하지 않은 경우 `from_pretrained` 메소드를 사용하여 모델의 기본 특성 추출기 ㅁ개변수를 불러 오면 됩니다.
+
+
+
+사용자 지정 특성 추출기를 만들려면 [`Wav2Vec2FeatureExtractor`] 매개변수를 수정합니다:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> w2v2_extractor = Wav2Vec2FeatureExtractor(sampling_rate=8000, do_normalize=False)
+>>> print(w2v2_extractor)
+Wav2Vec2FeatureExtractor {
+ "do_normalize": false,
+ "feature_extractor_type": "Wav2Vec2FeatureExtractor",
+ "feature_size": 1,
+ "padding_side": "right",
+ "padding_value": 0.0,
+ "return_attention_mask": false,
+ "sampling_rate": 8000
+}
+```
+
+
+## 프로세서[[processor]]
+
+멀티모달 작업을 지원하는 모델의 경우, 🤗 Transformers는 특성 추출기 및 토크나이저와 같은 처리 클래스를 단일 객체로 편리하게 래핑하는 프로세서 클래스를 제공합니다. 예를 들어, 자동 음성 인식 작업(Automatic Speech Recognition task (ASR))에 [`Wav2Vec2Processor`]를 사용한다고 가정해 보겠습니다. 자동 음성 인식 작업은 오디오를 텍스트로 변환하므로 특성 추출기와 토크나이저가 필요합니다.
+
+오디오 입력을 처리할 특성 추출기를 만듭니다:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> feature_extractor = Wav2Vec2FeatureExtractor(padding_value=1.0, do_normalize=True)
+```
+
+텍스트 입력을 처리할 토크나이저를 만듭니다:
+
+```py
+>>> from transformers import Wav2Vec2CTCTokenizer
+
+>>> tokenizer = Wav2Vec2CTCTokenizer(vocab_file="my_vocab_file.txt")
+```
+
+[`Wav2Vec2Processor`]에서 특성 추출기와 토크나이저를 결합합니다:
+
+```py
+>>> from transformers import Wav2Vec2Processor
+
+>>> processor = Wav2Vec2Processor(feature_extractor=feature_extractor, tokenizer=tokenizer)
+```
+
+configuration과 모델이라는 두 가지 기본 클래스와 추가 전처리 클래스(토크나이저, 이미지 프로세서, 특성 추출기 또는 프로세서)를 사용하면 🤗 Transformers에서 지원하는 모든 모델을 만들 수 있습니다. 이러한 각 기본 클래스는 구성이 가능하므로 원하는 특정 속성을 사용할 수 있습니다. 학습을 위해 모델을 쉽게 설정하거나 기존의 사전 학습된 모델을 수정하여 미세 조정할 수 있습니다.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/custom_models.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/custom_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..cb67a535b47d41453e2b5d27fcc67b89a7ab7407
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/custom_models.md
@@ -0,0 +1,346 @@
+
+
+# 사용자 정의 모델 공유하기[[sharing-custom-models]]
+
+🤗 Transformers 라이브러리는 쉽게 확장할 수 있도록 설계되었습니다.
+모든 모델은 추상화 없이 저장소의 지정된 하위 폴더에 완전히 코딩되어 있으므로, 손쉽게 모델링 파일을 복사하고 필요에 따라 조정할 수 있습니다.
+
+완전히 새로운 모델을 만드는 경우에는 처음부터 시작하는 것이 더 쉬울 수 있습니다.
+이 튜토리얼에서는 Transformers 내에서 사용할 수 있도록 사용자 정의 모델과 구성을 작성하는 방법과
+🤗 Transformers 라이브러리에 없는 경우에도 누구나 사용할 수 있도록 (의존성과 함께) 커뮤니티에 공유하는 방법을 배울 수 있습니다.
+
+[timm 라이브러리](https://github.com/rwightman/pytorch-image-models)의 ResNet 클래스를 [`PreTrainedModel`]로 래핑한 ResNet 모델을 예로 모든 것을 설명합니다.
+
+## 사용자 정의 구성 작성하기[[writing-a-custom-configuration]]
+
+모델에 들어가기 전에 먼저 구성을 작성해보도록 하겠습니다.
+모델의 `configuration`은 모델을 만들기 위해 필요한 모든 중요한 것들을 포함하고 있는 객체입니다.
+다음 섹션에서 볼 수 있듯이, 모델은 `config`를 사용해서만 초기화할 수 있기 때문에 완벽한 구성이 필요합니다.
+
+아래 예시에서는 ResNet 클래스의 인수(argument)를 조정해보겠습니다.
+다른 구성은 가능한 ResNet 중 다른 유형을 제공합니다.
+그런 다음 몇 가지 유효성을 확인한 후 해당 인수를 저장합니다.
+
+```python
+from transformers import PretrainedConfig
+from typing import List
+
+
+class ResnetConfig(PretrainedConfig):
+ model_type = "resnet"
+
+ def __init__(
+ self,
+ block_type="bottleneck",
+ layers: List[int] = [3, 4, 6, 3],
+ num_classes: int = 1000,
+ input_channels: int = 3,
+ cardinality: int = 1,
+ base_width: int = 64,
+ stem_width: int = 64,
+ stem_type: str = "",
+ avg_down: bool = False,
+ **kwargs,
+ ):
+ if block_type not in ["basic", "bottleneck"]:
+ raise ValueError(f"`block_type` must be 'basic' or bottleneck', got {block_type}.")
+ if stem_type not in ["", "deep", "deep-tiered"]:
+ raise ValueError(f"`stem_type` must be '', 'deep' or 'deep-tiered', got {stem_type}.")
+
+ self.block_type = block_type
+ self.layers = layers
+ self.num_classes = num_classes
+ self.input_channels = input_channels
+ self.cardinality = cardinality
+ self.base_width = base_width
+ self.stem_width = stem_width
+ self.stem_type = stem_type
+ self.avg_down = avg_down
+ super().__init__(**kwargs)
+```
+
+사용자 정의 `configuration`을 작성할 때 기억해야 할 세 가지 중요한 사항은 다음과 같습니다:
+- `PretrainedConfig`을 상속해야 합니다.
+- `PretrainedConfig`의 `__init__`은 모든 kwargs를 허용해야 하고,
+- 이러한 `kwargs`는 상위 클래스 `__init__`에 전달되어야 합니다.
+
+상속은 🤗 Transformers 라이브러리에서 모든 기능을 가져오는 것입니다.
+이러한 점으로부터 비롯되는 두 가지 제약 조건은 `PretrainedConfig`에 설정하는 것보다 더 많은 필드가 있습니다.
+`from_pretrained` 메서드로 구성을 다시 로드할 때 해당 필드는 구성에서 수락한 후 상위 클래스로 보내야 합니다.
+
+모델을 auto 클래스에 등록하지 않는 한, `configuration`에서 `model_type`을 정의(여기서 `model_type="resnet"`)하는 것은 필수 사항이 아닙니다 (마지막 섹션 참조).
+
+이렇게 하면 라이브러리의 다른 모델 구성과 마찬가지로 구성을 쉽게 만들고 저장할 수 있습니다.
+다음은 resnet50d 구성을 생성하고 저장하는 방법입니다:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d_config.save_pretrained("custom-resnet")
+```
+
+이렇게 하면 `custom-resnet` 폴더 안에 `config.json`이라는 파일이 저장됩니다.
+그런 다음 `from_pretrained` 메서드를 사용하여 구성을 다시 로드할 수 있습니다.
+
+```py
+resnet50d_config = ResnetConfig.from_pretrained("custom-resnet")
+```
+
+구성을 Hub에 직접 업로드하기 위해 [`PretrainedConfig`] 클래스의 [`~PretrainedConfig.push_to_hub`]와 같은 다른 메서드를 사용할 수 있습니다.
+
+
+## 사용자 정의 모델 작성하기[[writing-a-custom-model]]
+
+이제 ResNet 구성이 있으므로 모델을 작성할 수 있습니다.
+실제로는 두 개를 작성할 것입니다. 하나는 이미지 배치에서 hidden features를 추출하는 것([`BertModel`]과 같이), 다른 하나는 이미지 분류에 적합한 것입니다([`BertForSequenceClassification`]과 같이).
+
+이전에 언급했듯이 이 예제에서는 단순하게 하기 위해 모델의 느슨한 래퍼(loose wrapper)만 작성할 것입니다.
+이 클래스를 작성하기 전에 블록 유형과 실제 블록 클래스 간의 매핑 작업만 하면 됩니다.
+그런 다음 `ResNet` 클래스로 전달되어 `configuration`을 통해 모델이 선언됩니다:
+
+```py
+from transformers import PreTrainedModel
+from timm.models.resnet import BasicBlock, Bottleneck, ResNet
+from .configuration_resnet import ResnetConfig
+
+
+BLOCK_MAPPING = {"basic": BasicBlock, "bottleneck": Bottleneck}
+
+
+class ResnetModel(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor):
+ return self.model.forward_features(tensor)
+```
+
+이미지 분류 모델을 만들기 위해서는 forward 메소드만 변경하면 됩니다:
+
+```py
+import torch
+
+
+class ResnetModelForImageClassification(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor, labels=None):
+ logits = self.model(tensor)
+ if labels is not None:
+ loss = torch.nn.functional.cross_entropy(logits, labels)
+ return {"loss": loss, "logits": logits}
+ return {"logits": logits}
+```
+
+두 경우 모두 `PreTrainedModel`를 상속받고, `config`를 통해 상위 클래스 초기화를 호출하다는 점을 기억하세요 (일반적인 `torch.nn.Module`을 작성할 때와 비슷함).
+모델을 auto 클래스에 등록하고 싶은 경우에는 `config_class`를 설정하는 부분이 필수입니다 (마지막 섹션 참조).
+
+
+
+라이브러리에 존재하는 모델과 굉장히 유사하다면, 모델을 생성할 때 구성을 참조해 재사용할 수 있습니다.
+
+
+
+원하는 것을 모델이 반환하도록 할 수 있지만, `ResnetModelForImageClassification`에서 했던 것 처럼
+레이블을 통과시켰을 때 손실과 함께 사전 형태로 반환하는 것이 [`Trainer`] 클래스 내에서 직접 모델을 사용하기에 유용합니다.
+자신만의 학습 루프 또는 다른 학습 라이브러리를 사용할 계획이라면 다른 출력 형식을 사용해도 좋습니다.
+
+이제 모델 클래스가 있으므로 하나 생성해 보겠습니다:
+
+```py
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+```
+
+다시 말하지만, [`~PreTrainedModel.save_pretrained`]또는 [`~PreTrainedModel.push_to_hub`]처럼 [`PreTrainedModel`]에 속하는 모든 메소드를 사용할 수 있습니다.
+다음 섹션에서 두 번째 메소드를 사용해 모델 코드와 모델 가중치를 업로드하는 방법을 살펴보겠습니다.
+먼저, 모델 내부에 사전 훈련된 가중치를 로드해 보겠습니다.
+
+이 예제를 활용할 때는, 사용자 정의 모델을 자신만의 데이터로 학습시킬 것입니다.
+이 튜토리얼에서는 빠르게 진행하기 위해 사전 훈련된 resnet50d를 사용하겠습니다.
+아래 모델은 resnet50d의 래퍼이기 때문에, 가중치를 쉽게 로드할 수 있습니다.
+
+
+```py
+import timm
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+이제 [`~PreTrainedModel.save_pretrained`] 또는 [`~PreTrainedModel.push_to_hub`]를 사용할 때 모델 코드가 저장되는지 확인해봅시다.
+
+## Hub로 코드 업로드하기[[sending-the-code-to-the-hub]]
+
+
+
+이 API는 실험적이며 다음 릴리스에서 약간의 변경 사항이 있을 수 있습니다.
+
+
+
+먼저 모델이 `.py` 파일에 완전히 정의되어 있는지 확인하세요.
+모든 파일이 동일한 작업 경로에 있기 때문에 상대경로 임포트(relative import)에 의존할 수 있습니다 (transformers에서는 이 기능에 대한 하위 모듈을 지원하지 않습니다).
+이 예시에서는 작업 경로 안의 `resnet_model`에서 `modeling_resnet.py` 파일과 `configuration_resnet.py` 파일을 정의합니다.
+구성 파일에는 `ResnetConfig`에 대한 코드가 있고 모델링 파일에는 `ResnetModel` 및 `ResnetModelForImageClassification`에 대한 코드가 있습니다.
+
+```
+.
+└── resnet_model
+ ├── __init__.py
+ ├── configuration_resnet.py
+ └── modeling_resnet.py
+```
+
+Python이 `resnet_model`을 모듈로 사용할 수 있도록 감지하는 목적이기 때문에 `__init__.py`는 비어 있을 수 있습니다.
+
+
+
+라이브러리에서 모델링 파일을 복사하는 경우,
+모든 파일 상단에 있는 상대 경로 임포트(relative import) 부분을 `transformers` 패키지에서 임포트 하도록 변경해야 합니다.
+
+
+
+기존 구성이나 모델을 재사용(또는 서브 클래스화)할 수 있습니다.
+
+커뮤니티에 모델을 공유하기 위해서는 다음 단계를 따라야 합니다:
+먼저, 새로 만든 파일에 ResNet 모델과 구성을 임포트합니다:
+
+```py
+from resnet_model.configuration_resnet import ResnetConfig
+from resnet_model.modeling_resnet import ResnetModel, ResnetModelForImageClassification
+```
+
+다음으로 `save_pretrained` 메소드를 사용해 해당 객체의 코드 파일을 복사하고,
+복사한 파일을 Auto 클래스로 등록하고(모델인 경우) 실행합니다:
+
+```py
+ResnetConfig.register_for_auto_class()
+ResnetModel.register_for_auto_class("AutoModel")
+ResnetModelForImageClassification.register_for_auto_class("AutoModelForImageClassification")
+```
+
+`configuration`에 대한 auto 클래스를 지정할 필요는 없지만(`configuration` 관련 auto 클래스는 AutoConfig 클래스 하나만 있음), 모델의 경우에는 지정해야 합니다.
+사용자 지정 모델은 다양한 작업에 적합할 수 있으므로, 모델에 맞는 auto 클래스를 지정해야 합니다.
+
+다음으로, 이전에 작업했던 것과 마찬가지로 구성과 모델을 작성합니다:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+이제 모델을 Hub로 업로드하기 위해 로그인 상태인지 확인하세요.
+터미널에서 다음 코드를 실행해 확인할 수 있습니다:
+
+```bash
+huggingface-cli login
+```
+
+주피터 노트북의 경우에는 다음과 같습니다:
+
+```py
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+그런 다음 이렇게 자신의 네임스페이스(또는 자신이 속한 조직)에 업로드할 수 있습니다:
+```py
+resnet50d.push_to_hub("custom-resnet50d")
+```
+
+On top of the modeling weights and the configuration in json format, this also copied the modeling and
+configuration `.py` files in the folder `custom-resnet50d` and uploaded the result to the Hub. You can check the result
+in this [model repo](https://huggingface.co/sgugger/custom-resnet50d).
+json 형식의 모델링 가중치와 구성 외에도 `custom-resnet50d` 폴더 안의 모델링과 구성 `.py` 파일을 복사하해 Hub에 업로드합니다.
+[모델 저장소](https://huggingface.co/sgugger/custom-resnet50d)에서 결과를 확인할 수 있습니다.
+
+[sharing tutorial](model_sharing) 문서의 `push_to_hub` 메소드에서 자세한 내용을 확인할 수 있습니다.
+
+
+## 사용자 정의 코드로 모델 사용하기[[using-a-model-with-custom-code]]
+
+auto 클래스와 `from_pretrained` 메소드를 사용하여 사용자 지정 코드 파일과 함께 모든 구성, 모델, 토크나이저를 사용할 수 있습니다.
+Hub에 업로드된 모든 파일 및 코드는 멜웨어가 있는지 검사되지만 (자세한 내용은 [Hub 보안](https://huggingface.co/docs/hub/security#malware-scanning) 설명 참조),
+자신의 컴퓨터에서 모델 코드와 작성자가 악성 코드를 실행하지 않는지 확인해야 합니다.
+사용자 정의 코드로 모델을 사용하려면 `trust_remote_code=True`로 설정하세요:
+
+```py
+from transformers import AutoModelForImageClassification
+
+model = AutoModelForImageClassification.from_pretrained("sgugger/custom-resnet50d", trust_remote_code=True)
+```
+
+모델 작성자가 악의적으로 코드를 업데이트하지 않았다는 점을 확인하기 위해, 커밋 해시(commit hash)를 `revision`으로 전달하는 것도 강력히 권장됩니다 (모델 작성자를 완전히 신뢰하지 않는 경우).
+
+```py
+commit_hash = "ed94a7c6247d8aedce4647f00f20de6875b5b292"
+model = AutoModelForImageClassification.from_pretrained(
+ "sgugger/custom-resnet50d", trust_remote_code=True, revision=commit_hash
+)
+```
+
+Hub에서 모델 저장소의 커밋 기록을 찾아볼 때, 모든 커밋의 커밋 해시를 쉽게 복사할 수 있는 버튼이 있습니다.
+
+## 사용자 정의 코드로 만든 모델을 auto 클래스로 등록하기[[registering-a-model-with-custom-code-to-the-auto-classes]]
+
+🤗 Transformers를 상속하는 라이브러리를 작성하는 경우 사용자 정의 모델을 auto 클래스에 추가할 수 있습니다.
+사용자 정의 모델을 사용하기 위해 해당 라이브러리를 임포트해야 하기 때문에, 이는 Hub로 코드를 업로드하는 것과 다릅니다 (Hub에서 자동적으로 모델 코드를 다운로드 하는 것과 반대).
+
+구성에 기존 모델 유형과 다른 `model_type` 속성이 있고 모델 클래스에 올바른 `config_class` 속성이 있는 한,
+다음과 같이 auto 클래스에 추가할 수 있습니다:
+
+```py
+from transformers import AutoConfig, AutoModel, AutoModelForImageClassification
+
+AutoConfig.register("resnet", ResnetConfig)
+AutoModel.register(ResnetConfig, ResnetModel)
+AutoModelForImageClassification.register(ResnetConfig, ResnetModelForImageClassification)
+```
+
+사용자 정의 구성을 [`AutoConfig`]에 등록할 때 사용되는 첫 번째 인수는 사용자 정의 구성의 `model_type`과 일치해야 합니다.
+또한, 사용자 정의 모델을 auto 클래스에 등록할 때 사용되는 첫 번째 인수는 해당 모델의 `config_class`와 일치해야 합니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/debugging.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/debugging.md
new file mode 100644
index 0000000000000000000000000000000000000000..24b2c7b04b509d9301003a3911dbb0b0e324eedf
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/debugging.md
@@ -0,0 +1,306 @@
+
+
+# 디버깅 [[debugging]]
+
+## Multi-GPU 네트워크 문제 디버그 [[multigpu-network-issues-debug]]
+
+`DistributedDataParallel` 및 다중 GPU를 사용하여 훈련하거나 추론할 때, 프로세스 및/또는 노드 간의 상호 통신 문제가 발생하는 경우, 다음 스크립트를 사용하여 네트워크 문제를 진단할 수 있습니다.
+
+```bash
+wget https://raw.githubusercontent.com/huggingface/transformers/main/scripts/distributed/torch-distributed-gpu-test.py
+```
+
+예를 들어, 2개의 GPU가 상호 작용하는 방식을 테스트하려면 다음을 실행하세요:
+
+```bash
+python -m torch.distributed.run --nproc_per_node 2 --nnodes 1 torch-distributed-gpu-test.py
+```
+두 프로세스가 서로 통신하고 GPU 메모리를 할당하는 경우, 각각 "OK" 상태를 출력합니다.
+
+더 많은 GPU 또는 노드의 경우 스크립트의 인수를 조정하면 됩니다.
+
+진단 스크립트 내에서 더 많은 세부 정보와 SLURM 환경에서 실행하는 방법에 대한 레시피를 찾을 수 있습니다.
+
+추가적인 디버그 수준은 다음과 같이 `NCCL_DEBUG=INFO` 환경 변수를 추가하는 것입니다:
+
+```bash
+NCCL_DEBUG=INFO python -m torch.distributed.run --nproc_per_node 2 --nnodes 1 torch-distributed-gpu-test.py
+```
+
+이렇게 하면 NCCL 관련 디버그 정보가 많이 출력되며, 문제가 보고된 경우에는 인터넷에서 검색할 수 있습니다. 또는 출력을 해석하는 방법을 잘 모르는 경우 로그 파일을 이슈에 공유할 수 있습니다.
+
+
+
+## 언더플로 및 오버플로 감지 [[underflow-and-overflow-detection]]
+
+
+
+
+이 기능은 현재 PyTorch에서만 사용할 수 있습니다.
+
+
+
+
+
+다중 GPU 훈련을 위해서는 DDP (`torch.distributed.launch`)가 필요합니다.
+
+
+
+
+
+이 기능은 `nn.Module`을 기반으로 하는 모델과 함께 사용할 수 있습니다.
+
+
+
+`loss=NaN`이 나타나거나 모델이 `inf` 또는 `nan`으로 인해 다른 이상한 동작을 하는 경우, 언더플로 또는 오버플로의 첫 번째 발생 위치와 그 원인을 파악해야 합니다. 다행히도 이를 자동으로 감지하는 특수 모듈을 활성화하여 쉽게 알아낼 수 있습니다.
+
+[`Trainer`]를 사용하는 경우, 다음을 기존의 명령줄 인수에 추가하면 됩니다.
+
+```bash
+--debug underflow_overflow
+```
+또는 [`TrainingArguments`] 객체를 생성할 때 `debug="underflow_overflow"`를 전달합니다.
+
+자체 훈련 루프나 다른 Trainer를 사용하는 경우, 다음과 같이 수행할 수 있습니다.
+
+```python
+from transformers.debug_utils import DebugUnderflowOverflow
+
+debug_overflow = DebugUnderflowOverflow(model)
+```
+
+[`~debug_utils.DebugUnderflowOverflow`]는 모델에 후크를 삽입하여 각 forward 호출 직후에 입력 및 출력 변수 및 해당 모듈의 가중치를 테스트합니다. 활성화나 가중치의 최소한 하나의 요소에서 `inf` 또는 `nan`이 감지되면 프로그램이 어설트되고 다음과 같은 보고서가 출력됩니다. (이 예제는 fp16 혼합 정밀도에서 `google/mt5-small`에서 캡처된 것입니다):
+
+```
+Detected inf/nan during batch_number=0
+Last 21 forward frames:
+abs min abs max metadata
+ encoder.block.1.layer.1.DenseReluDense.dropout Dropout
+0.00e+00 2.57e+02 input[0]
+0.00e+00 2.85e+02 output
+[...]
+ encoder.block.2.layer.0 T5LayerSelfAttention
+6.78e-04 3.15e+03 input[0]
+2.65e-04 3.42e+03 output[0]
+ None output[1]
+2.25e-01 1.00e+04 output[2]
+ encoder.block.2.layer.1.layer_norm T5LayerNorm
+8.69e-02 4.18e-01 weight
+2.65e-04 3.42e+03 input[0]
+1.79e-06 4.65e+00 output
+ encoder.block.2.layer.1.DenseReluDense.wi_0 Linear
+2.17e-07 4.50e+00 weight
+1.79e-06 4.65e+00 input[0]
+2.68e-06 3.70e+01 output
+ encoder.block.2.layer.1.DenseReluDense.wi_1 Linear
+8.08e-07 2.66e+01 weight
+1.79e-06 4.65e+00 input[0]
+1.27e-04 2.37e+02 output
+ encoder.block.2.layer.1.DenseReluDense.dropout Dropout
+0.00e+00 8.76e+03 input[0]
+0.00e+00 9.74e+03 output
+ encoder.block.2.layer.1.DenseReluDense.wo Linear
+1.01e-06 6.44e+00 weight
+0.00e+00 9.74e+03 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.DenseReluDense T5DenseGatedGeluDense
+1.79e-06 4.65e+00 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.dropout Dropout
+3.18e-04 6.27e+04 input[0]
+0.00e+00 inf output
+```
+
+예제 출력은 간략성을 위해 중간 부분이 잘려 있습니다.
+
+두 번째 열은 절대적으로 가장 큰 요소의 값이며, 따라서 마지막 몇 개의 프레임을 자세히 살펴보면 입력과 출력이 `1e4` 범위에 있음을 알 수 있습니다. 따라서 이 훈련은 `fp16` 혼합 정밀도로 수행될 때 가장 마지막 단계에서 오버플로우가 발생했습니다 (`fp16`에서 `inf` 이전의 가장 큰 숫자는 `64e3`입니다). `fp16` 아래에서 오버플로우를 피하기 위해서는 활성화는 `1e4`보다 훨씬 작아야 합니다. 왜냐하면 `1e4 * 1e4 = 1e8`이기 때문에 큰 활성화와의 행렬 곱은 수치적인 오버플로우 조건으로 이어질 것입니다.
+
+추적의 맨 처음에서 어느 배치 번호에서 문제가 발생했는지 알 수 있습니다 (여기서 `Detected inf/nan during batch_number=0`은 문제가 첫 번째 배치에서 발생했음을 의미합니다).
+
+각 보고된 프레임은 해당 프레임이 보고하는 해당 모듈에 대한 완전한 항목을 선언하며, 이 프레임만 살펴보면 다음과 같습니다.
+
+```
+ encoder.block.2.layer.1.layer_norm T5LayerNorm
+8.69e-02 4.18e-01 weight
+2.65e-04 3.42e+03 input[0]
+1.79e-06 4.65e+00 output
+```
+
+여기서 `encoder.block.2.layer.1.layer_norm`은 인코더의 두 번째 블록의 첫 번째 레이어에 대한 레이어 정규화를 의미하며, `forward`의 특정 호출은 `T5LayerNorm`입니다.
+
+이 보고서의 마지막 몇 개 프레임을 살펴보겠습니다:
+
+```
+Detected inf/nan during batch_number=0
+Last 21 forward frames:
+abs min abs max metadata
+[...]
+ encoder.block.2.layer.1.DenseReluDense.wi_0 Linear
+2.17e-07 4.50e+00 weight
+1.79e-06 4.65e+00 input[0]
+2.68e-06 3.70e+01 output
+ encoder.block.2.layer.1.DenseReluDense.wi_1 Linear
+8.08e-07 2.66e+01 weight
+1.79e-06 4.65e+00 input[0]
+1.27e-04 2.37e+02 output
+ encoder.block.2.layer.1.DenseReluDense.wo Linear
+1.01e-06 6.44e+00 weight
+0.00e+00 9.74e+03 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.DenseReluDense T5DenseGatedGeluDense
+1.79e-06 4.65e+00 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.dropout Dropout
+3.18e-04 6.27e+04 input[0]
+0.00e+00 inf output
+```
+
+마지막 프레임은 `Dropout.forward` 함수에 대한 보고입니다. 첫 번째 항목은 유일한 입력을 나타내고 두 번째 항목은 유일한 출력을 나타냅니다. 이 함수가 `DenseReluDense` 클래스 내부의 `dropout` 속성에서 호출된 것을 볼 수 있습니다. 이는 첫 번째 레이어의 두 번째 블록에서 첫 번째 배치 중에 발생했다는 것을 알 수 있습니다. 마지막으로, 절대적으로 가장 큰 입력 요소는 `6.27e+04`이고 출력도 마찬가지로 `inf`입니다.
+
+여기에서는 `T5DenseGatedGeluDense.forward`가 출력 활성화를 생성하는데, 절대적으로 가장 큰 값이 약 62.7K인 것을 볼 수 있습니다. 이 값은 fp16의 최대 제한인 64K에 매우 근접합니다. 다음 프레임에서는 일부 요소를 0으로 만든 후 가중치를 재정규화하는 `Dropout`이 있습니다. 이로 인해 절대 최대값이 64K를 초과하고 오버플로우(`inf`)가 발생합니다.
+
+보시다시피, fp16 숫자의 경우 숫자가 매우 커질 때 이전 프레임을 살펴보아야 합니다.
+
+보고서를 `models/t5/modeling_t5.py`의 코드와 일치시켜 보겠습니다.
+
+```python
+class T5DenseGatedGeluDense(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.wi_0 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wi_1 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wo = nn.Linear(config.d_ff, config.d_model, bias=False)
+ self.dropout = nn.Dropout(config.dropout_rate)
+ self.gelu_act = ACT2FN["gelu_new"]
+
+ def forward(self, hidden_states):
+ hidden_gelu = self.gelu_act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+```
+
+이제 `dropout` 호출과 이전의 모든 호출을 쉽게 확인할 수 있습니다.
+
+감지는 `forward` 후크에서 발생하므로, 이러한 보고서는 각 `forward`가 반환된 직후에 즉시 출력됩니다.
+
+전체 보고서로 돌아가서 문제에 대한 조치 및 수정을 하려면, 숫자가 증가하기 시작한 몇 개의 프레임 위로 이동해서 여기서 `fp32` 모드로 전환해야 합니다. 이렇게 해야 숫자가 곱해지거나 합쳐질 때 오버플로우되지 않을 가능성이 높습니다. 물론 다른 해결책도 있을 수 있습니다. 예를 들어, `amp`가 활성화된 경우 일시적으로 끄고 원래의 `forward`를 도우미 래퍼로 이동한 후 다음과 같이 할 수 있습니다:
+
+```python
+def _forward(self, hidden_states):
+ hidden_gelu = self.gelu_act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+import torch
+
+
+def forward(self, hidden_states):
+ if torch.is_autocast_enabled():
+ with torch.cuda.amp.autocast(enabled=False):
+ return self._forward(hidden_states)
+ else:
+ return self._forward(hidden_states)
+```
+
+자동 감지기는 전체 프레임의 입력과 출력에 대해서만 보고하므로, 어디를 살펴봐야 하는지 알면 특정 `forward` 함수의 중간 단계도 분석할 수 있습니다. 이 경우에는 `detect_overflow` 도우미 함수를 사용하여 원하는 위치에 감지기를 삽입할 수 있습니다. 예를 들어:
+
+```python
+from debug_utils import detect_overflow
+
+
+class T5LayerFF(nn.Module):
+ [...]
+
+ def forward(self, hidden_states):
+ forwarded_states = self.layer_norm(hidden_states)
+ detect_overflow(forwarded_states, "after layer_norm")
+ forwarded_states = self.DenseReluDense(forwarded_states)
+ detect_overflow(forwarded_states, "after DenseReluDense")
+ return hidden_states + self.dropout(forwarded_states)
+```
+
+여기서는 이를 추가하여 2개의 것을 추적하고 이제 `forwarded_states`의 `inf` 또는 `nan`이 중간에 감지되었는지를 추적합니다.
+
+실제로 위의 예제에서 각 호출이 `nn.Module`이기 때문에 탐지기가 이미 이를 보고합니다. 로컬에서 직접 계산하는 경우 이렇게 수행한다고 가정해 봅시다.
+
+또한, 자체 코드에서 디버거를 인스턴스화하는 경우 기본값에서 출력되는 프레임 수를 조정할 수 있습니다. 예를 들어:
+
+```python
+from transformers.debug_utils import DebugUnderflowOverflow
+
+debug_overflow = DebugUnderflowOverflow(model, max_frames_to_save=100)
+```
+
+### 특정 배치의 절댓값 최소 및 최대 값 추적 [[specific-batch-absolute-min-and-max-value-tracing]]
+
+동일한 디버깅 클래스는 언더플로우/오버플로우 감지 기능이 꺼진 상태에서 배치별 추적에도 사용할 수 있습니다.
+
+예를 들어, 특정 배치의 각 `forward` 호출의 모든 구성 성분에 대한 절대 최솟값과 최댓값을 확인하고, 이를 배치 1과 3에 대해서만 수행하려면 다음과 같이 이 클래스를 인스턴스화합니다:
+
+```python
+debug_overflow = DebugUnderflowOverflow(model, trace_batch_nums=[1, 3])
+```
+
+그러면 이제 배치 1과 3 전체가 언더플로우/오버플로우 감지기와 동일한 형식으로 추적됩니다.
+
+배치는 0부터 시작합니다.
+
+이는 프로그램이 특정 배치 번호 이후에 오작동하기 시작하는 것을 알고 있는 경우에 유용합니다. 그렇기 때문에 해당 영역으로 바로 이동할 수 있습니다. 이런 구성에 대한 샘플 축소된 출력은 다음과 같습니다.
+
+```
+ *** Starting batch number=1 ***
+abs min abs max metadata
+ shared Embedding
+1.01e-06 7.92e+02 weight
+0.00e+00 2.47e+04 input[0]
+5.36e-05 7.92e+02 output
+[...]
+ decoder.dropout Dropout
+1.60e-07 2.27e+01 input[0]
+0.00e+00 2.52e+01 output
+ decoder T5Stack
+ not a tensor output
+ lm_head Linear
+1.01e-06 7.92e+02 weight
+0.00e+00 1.11e+00 input[0]
+6.06e-02 8.39e+01 output
+ T5ForConditionalGeneration
+ not a tensor output
+
+ *** Starting batch number=3 ***
+abs min abs max metadata
+ shared Embedding
+1.01e-06 7.92e+02 weight
+0.00e+00 2.78e+04 input[0]
+5.36e-05 7.92e+02 output
+[...]
+```
+
+여기에서는 모델의 forward 호출 수와 동일한 수의 프레임이 덤프되므로 많은 수의 프레임이 생성됩니다. 따라서 원하는 것일 수도 있고 아닐 수도 있습니다. 그러나 때로는 일반 디버거보다 디버깅 목적으로 더 쉽게 사용할 수 있습니다. 예를 들어, 문제가 배치 번호 150에서 시작하는 경우 149와 150의 추적을 덤프하고 숫자가 어디서부터 다르게 되었는지 비교할 수 있습니다.
+
+또한, 훈련을 중지할 배치 번호를 지정할 수도 있습니다. 다음과 같이 지정할 수 있습니다.
+
+```python
+debug_overflow = DebugUnderflowOverflow(model, trace_batch_nums=[1, 3], abort_after_batch_num=3)
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/deepspeed.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/deepspeed.md
new file mode 100644
index 0000000000000000000000000000000000000000..9945e298b7763e16ea0c51dfa9e84a4bbfdca412
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/deepspeed.md
@@ -0,0 +1,1220 @@
+
+
+# DeepSpeed[[deepspeed]]
+
+[DeepSpeed](https://www.deepspeed.ai/)는 분산 학습 메모리를 효율적이고 빠르게 만드는 PyTorch 최적화 라이브러리입니다. 그 핵심은 대규모 모델을 규모에 맞게 훈련할 수 있는 [Zero Redundancy Optimizer(ZeRO)](https://hf.co/papers/1910.02054)입니다. ZeRO는 여러 단계로 작동합니다:
+
+* ZeRO-1, GPU 간 최적화 상태 분할
+* ZeRO-2, GPU 간 그레이디언트 분할
+* ZeRO-3, GPU 간 매개변수 분할
+
+GPU가 제한된 환경에서 ZeRO는 최적화 메모리와 계산을 GPU에서 CPU로 오프로드하여 단일 GPU에 대규모 모델을 장착하고 훈련할 수 있습니다. DeepSpeed는 모든 ZeRO 단계 및 오프로딩을 위해 Transformers [`Trainer`] 클래스와 통합되어 있습니다. 구성 파일을 제공하거나 제공된 템플릿을 사용하기만 하면 됩니다. 추론의 경우, Transformers는 대용량 모델을 가져올 수 있으므로 ZeRO-3 및 오프로딩을 지원합니다.
+
+이 가이드에서는 DeepSpeed 트레이닝을 배포하는 방법, 활성화할 수 있는 기능, 다양한 ZeRO 단계에 대한 구성 파일 설정 방법, 오프로딩, 추론 및 [`Trainer`] 없이 DeepSpeed를 사용하는 방법을 안내해 드립니다.
+
+## 설치[[installation]]
+
+DeepSpeed는 PyPI 또는 Transformers에서 설치할 수 있습니다(자세한 설치 옵션은 DeepSpeed [설치 상세사항](https://www.deepspeed.ai/tutorials/advanced-install/) 또는 GitHub [README](https://github.com/microsoft/deepspeed#installation)를 참조하세요).
+
+
+
+DeepSpeed를 설치하는 데 문제가 있는 경우 [DeepSpeed CUDA 설치](../debugging#deepspeed-cuda-installation) 가이드를 확인하세요. DeepSpeed에는 pip 설치 가능한 PyPI 패키지로 설치할 수 있지만, 하드웨어에 가장 잘 맞고 PyPI 배포판에서는 제공되지 않는 1비트 Adam과 같은 특정 기능을 지원하려면 [소스에서 설치하기](https://www.deepspeed.ai/tutorials/advanced-install/#install-deepspeed-from-source)를 적극 권장합니다.
+
+
+
+
+
+
+```bash
+pip install deepspeed
+```
+
+
+
+
+```bash
+pip install transformers[deepspeed]
+```
+
+
+
+
+## 메모리 요구량[[memory-requirements]]
+
+시작하기 전에 모델에 맞는 충분한 GPU 및 CPU 메모리가 있는지 확인하는 것이 좋습니다. DeepSpeed는 필요한 CPU/GPU 메모리를 추정할 수 있는 도구를 제공합니다. 예를 들어, 단일 GPU에서 [bigscience/T0_3B](bigscience/T0_3B) 모델의 메모리 요구 사항을 추정할 수 있습니다:
+
+```bash
+$ python -c 'from transformers import AutoModel; \
+from deepspeed.runtime.zero.stage3 import estimate_zero3_model_states_mem_needs_all_live; \
+model = AutoModel.from_pretrained("bigscience/T0_3B"); \
+estimate_zero3_model_states_mem_needs_all_live(model, num_gpus_per_node=1, num_nodes=1)'
+[...]
+Estimated memory needed for params, optim states and gradients for a:
+HW: Setup with 1 node, 1 GPU per node.
+SW: Model with 2783M total params, 65M largest layer params.
+ per CPU | per GPU | Options
+ 70.00GB | 0.25GB | offload_param=cpu , offload_optimizer=cpu , zero_init=1
+ 70.00GB | 0.25GB | offload_param=cpu , offload_optimizer=cpu , zero_init=0
+ 62.23GB | 5.43GB | offload_param=none, offload_optimizer=cpu , zero_init=1
+ 62.23GB | 5.43GB | offload_param=none, offload_optimizer=cpu , zero_init=0
+ 0.37GB | 46.91GB | offload_param=none, offload_optimizer=none, zero_init=1
+ 15.56GB | 46.91GB | offload_param=none, offload_optimizer=none, zero_init=0
+```
+
+즉, CPU 오프로드가 없는 단일 80GB GPU 또는 오프로드 할 8GB GPU와 최대 60GB CPU가 필요합니다 (이는 매개변수, 최적화 상태 및 그레이디언트에 대한 메모리 요구 사항일 뿐이며 CUDA 커널 및 활성화에는 조금 더 필요합니다). 또한 더 작은 GPU를 대여하거나 구입하는 것이 더 저렴하지만 모델을 훈련하는 데 시간이 더 오래 걸리므로 비용과 속도 간의 균형을 고려해야 합니다.
+
+GPU 메모리가 충분하다면 CPU/NVMe 오프로드를 비활성화하여 모든 작업을 더 빠르게 처리하세요.
+
+## ZeRO 단계 설정하기[[select-a-zero-stage]]
+
+DeepSpeed를 설치하고 메모리 요구 사항을 더 잘 파악했다면 다음 단계는 사용할 ZeRO 스테이지를 선택하는 것입니다. 가장 빠르고 메모리 효율이 높은 순서대로 정렬하면 다음과 같습니다:
+
+| 속도 | 메모리 효율 |
+|------------------|------------------|
+| ZeRO-1 | ZeRO-3 + offload |
+| ZeRO-2 | ZeRO-3 |
+| ZeRO-2 + offload | ZeRO-2 + offload |
+| ZeRO-3 | ZeRO-2 |
+| ZeRO-3 + offload | ZeRO-1 |
+
+자신에게 가장 적합한 방법을 찾으려면 가장 빠른 방법부터 시작하고 메모리가 부족하면 더 느리지만 메모리 효율이 높은 다음 단계를 시도하세요. 속도와 메모리 사용량 사이의 적절한 균형을 찾기 위해 (가장 메모리 효율적이거나 가장 빠른 것부터 시작하여) 원하는 방향으로 자유롭게 작업하세요.
+
+일반적으로 사용할 수 있는 프로세스는 다음과 같습니다(배치 크기 1로 시작):
+
+1. 그레이디언트 체크포인팅 활성화
+2. ZeRO-2 시도
+3. ZeRO-2와 매개변수 오프로드 시도
+4. ZeRO-3 시도
+5. ZeRO-3과 매개변수 CPU 오프로드 시도
+6. ZeRO-3, 매개변수와 옵티마이저 CPU 오프로드 시도
+7. [`~GenerationMixin.generate`] 메소드를 사용하는 경우 더 좁은 빔 서치 검색 범위와 같은 다양한 기본값을 낮춰보기
+8. 전체 정밀도 가중치보다 반정밀도(구형 GPU 구조의 경우 fp16, 암페어 이후 GPU의 경우 bf16)를 혼합해보기
+9. 가능하면 하드웨어를 더 추가하거나 Infinity가 매개변수와 옵티마이저를 NVMe로 오프로드하도록 활성화
+10. 메모리가 부족하지 않으면 유효 처리량을 측정한 다음 배치 크기를 최대한 크게 늘려 GPU 효율성을 극대화
+11. 마지막으로 일부 오프로드 기능을 비활성화하거나 더 빠른 ZeRO 스테이지를 사용하고 배치 크기를 늘리거나 줄여 속도와 메모리 사용량 간의 최적의 균형을 찾아 트레이닝 설정을 최적화
+
+
+## DeepSpeed 구성 파일[[deepspeed-configuration-file]]
+
+DeepSpeed는 트레이닝 실행 방법을 구성하는 모든 매개변수가 포함된 구성 파일을 통해 [`Trainer`] 클래스와 함께 작동합니다. 트레이닝 스크립트를 실행하면 DeepSpeed는 [`Trainer`]로부터 받은 구성을 콘솔에 기록하므로 어떤 구성이 사용되었는지 정확히 확인할 수 있습니다.
+
+
+
+DeepSpeed 구성 옵션의 전체 목록은 [DeepSpeed Configuration JSON](https://www.deepspeed.ai/docs/config-json/)에서 확인할 수 있습니다. 또한 [DeepSpeedExamples](https://github.com/microsoft/DeepSpeedExamples) 리포지토리 또는 기본 [DeepSpeed](https://github.com/microsoft/DeepSpeed) 리포지토리에서 다양한 DeepSpeed 구성 예제에 대한 보다 실용적인 예제를 찾을 수 있습니다. 구체적인 예제를 빠르게 찾으려면 다음과 같이 하세요:
+
+```bash
+git clone https://github.com/microsoft/DeepSpeedExamples
+cd DeepSpeedExamples
+find . -name '*json'
+# Lamb 옵티마이저 샘플 찾기
+grep -i Lamb $(find . -name '*json')
+```
+
+
+
+명령줄 인터페이스에서 트레이닝하는 경우 DeepSpeed 구성 파일은 JSON 파일의 경로로 전달되거나 노트북 설정에서 [`Trainer`]를 사용하는 경우 중첩된 `dict` 객체로 전달됩니다.
+
+
+
+
+```py
+TrainingArguments(..., deepspeed="path/to/deepspeed_config.json")
+```
+
+
+
+
+```py
+ds_config_dict = dict(scheduler=scheduler_params, optimizer=optimizer_params)
+args = TrainingArguments(..., deepspeed=ds_config_dict)
+trainer = Trainer(model, args, ...)
+```
+
+
+
+
+### DeepSpeed와 Trainer 매개변수[[deepspeed-and-trainer-parameters]]
+
+구성 매개변수에는 세 가지 유형이 있습니다:
+
+1. 일부 구성 매개변수는 [`Trainer`]와 DeepSpeed가 공유하며, 정의가 충돌하는 경우 오류를 식별하기 어려울 수 있습니다. 이러한 공유 구성 매개변수는 [`Trainer`] 명령줄 인수에서 쉽게 설정할 수 있습니다.
+
+2. 모델 설정에서 자동으로 도출되는 일부 설정 매개변수는 수동으로 값을 조정할 필요가 없습니다. [`Trainer`]는 구성 값 `auto`를 사용하여 가장 정확하거나 효율적인 값을 설정합니다. 직접 구성 매개변수를 명시적으로 설정할 수도 있지만, [`Trainer`] 인수와 DeepSpeed 설정 매개변수가 일치하도록 주의해야 합니다. 일치하지 않으면 감지하기 매우 어려운 방식으로 훈련이 실패할 수 있습니다!
+
+3. 교육 요구 사항에 따라 수동으로 설정해야 하는 일부 설정 매개변수는 DeepSpeed에만 해당됩니다.
+
+DeepSpeed 구성을 수정하고 [`TrainingArguments`]를 편집할 수도 있습니다:
+
+1. 기본 구성으로 사용할 DeepSpeed 구성 파일을 생성하거나 로드합니다.
+2. 다음 DeepSpeed 구성을 기반으로 [`TrainingArguments`] 객체를 생성합니다.
+
+`scheduler.params.total_num_steps`와 같은 일부 값은 트레이닝 중 [`Trainer`]에 의해 계산됩니다.
+
+### ZeRO 구성[[zero-configuration]]
+
+세 가지 구성이 있으며, 각 구성은 서로 다른 ZeRO 단계에 해당합니다. 1단계는 확장성 측면에서 그다지 눈여겨볼만하지 않으므로 이 가이드에서는 2단계와 3단계에 중점을 둡니다. `zero_optimization` 구성에는 활성화할 항목과 구성 방법에 대한 모든 옵션이 포함되어 있습니다. 각 매개변수에 대한 자세한 설명은 [DeepSpeed 구성 JSON](https://www.deepspeed.ai/docs/config-json/) 참조를 참조하세요.
+
+
+DeepSpeed는 매개변수 이름의 유효성을 검사하지 않으며 오타가 있으면 매개변수의 기본 설정으로 대체합니다. DeepSpeed 엔진 시작 로그 메시지를 보고 어떤 값을 사용할지 확인할 수 있습니다.
+
+
+
+[`Trainer`]는 동등한 명령줄 인수를 제공하지 않으므로 다음 구성은 DeepSpeed로 설정해야 합니다.
+
+
+
+
+ZeRO-1은 옵티마이저 상태를 GPU에 분할하여 약간의 속도 향상을 기대할 수 있습니다. ZeRO-1 구성은 다음과 같이 설정할 수 있습니다:
+
+```yml
+{
+ "zero_optimization": {
+ "stage": 1
+ }
+}
+```
+
+
+
+
+ZeRO-2는 GPU에서 옵티마이저와 그레이디언트를 분할합니다. 이 단계는 추론과 관련이 없는 기능이기 때문에 주로 훈련에 사용됩니다. 더 나은 성능을 위해 구성해야 할 몇 가지 중요한 매개변수는 다음과 같습니다:
+
+* GPU 메모리 사용량을 줄이려면 `offload_optimizer`를 활성화해야 합니다.
+* `true`로 설정된 경우 `overlap_comm`은 GPU 메모리 사용량 증가를 상쇄하여 지연 시간을 줄입니다. 이 기능은 4.5배의 `allgather_bucket_size` 및 `reduce_bucket_size`값을 사용합니다. 이 예에서는 `5e8`로 설정되어 있으므로 9GB의 GPU 메모리가 필요합니다. GPU 메모리가 8GB 이하인 경우, 메모리 요구량을 낮추고 메모리 부족(OOM) 오류를 방지하기 위해 `overlap_comm`을 줄여야 합니다.
+* `allgather_bucket_size`와 `reduce_bucket_size`는 사용 가능한 GPU 메모리와 통신 속도를 절충합니다. 값이 작을수록 통신 속도가 느려지고 더 많은 GPU 메모리를 사용할 수 있습니다. 예를 들어, 배치 크기가 큰 것이 약간 느린 훈련 시간보다 더 중요한지 균형을 맞출 수 있습니다.
+* DeepSpeed 0.4.4에서는 CPU 오프로딩을 위해 `round_robin_gradients`를 사용할 수 있습니다. 이 기능은 세분화된 그레이디언트 파티셔닝을 통해 등급 간 그레이디언트 복사를 CPU 메모리로 병렬화합니다. 성능 이점은 그레이디언트 누적 단계(최적화 단계 간 복사 횟수 증가) 또는 GPU 수(병렬 처리 증가)에 따라 증가합니다.
+
+```yml
+{
+ "zero_optimization": {
+ "stage": 2,
+ "offload_optimizer": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "allgather_partitions": true,
+ "allgather_bucket_size": 5e8,
+ "overlap_comm": true,
+ "reduce_scatter": true,
+ "reduce_bucket_size": 5e8,
+ "contiguous_gradients": true
+ "round_robin_gradients": true
+ }
+}
+```
+
+
+
+
+ZeRO-3는 옵티마이저, 그래디언트, 매개변수를 여러 GPU에 걸쳐 분할합니다. ZeRO-2와 달리 ZeRO-3는 여러 GPU에 대규모 모델을 가져올 수 있기 때문에 훈련 외에도 추론에도 사용할 수 있습니다. 구성해야 할 몇 가지 중요한 매개변수는 다음과 같습니다:
+
+* `device: "cpu"` 는 GPU 메모리가 부족하고 사용 가능한 CPU 메모리가 있는 경우 도움이 될 수 있습니다. 이를 통해 모델 매개변수를 CPU로 오프로드할 수 있습니다.
+* `pin_memory: true` 는 처리량을 향상시킬 수 있지만, 핀 메모리는 메모리를 요청한 특정 프로세스를 위해 예약되어 있고 일반적으로 일반 CPU 메모리보다 훨씬 빠르게 액세스되기 때문에 다른 프로세스에서 사용할 수 있는 메모리가 줄어듭니다.
+* `stage3_max_live_parameters` 는 특정 시간에 GPU에 유지하려는 전체 매개변수의 상한값입니다. OOM 오류가 발생하면 이 값을 줄이세요.
+* `stage3_max_reuse_distance` 는 향후 매개변수를 다시 사용할 시기를 결정하는 값으로, 매개변수를 버릴지 유지할지 결정하는 데 도움이 됩니다. 매개변수를 재사용할 경우(`stage3_max_reuse_distance`보다 작은 값인 경우) 통신 오버헤드를 줄이기 위해 매개변수를 유지합니다. 이 기능은 활성화 체크포인팅이 활성화되어 있고 역전파 계산시까지 순전파 시점의 매개변수를 유지하려는 경우에 매우 유용합니다. 그러나 OOM 오류가 발생하면 이 값을 줄이세요.
+* 모델 저장 시 `stage3_gather_16bit_weights_on_model_save`는 fp16 가중치를 통합합니다. 대규모 모델을 학습하거나 여러 GPU를 사용할 경우 메모리와 속도 측면에서 비용이 많이 듭니다. 훈련을 재개할 계획이라면 이 옵션을 활성화해야 합니다.
+* `sub_group_size` 는 최적화 단계에서 업데이트되는 매개변수를 제어합니다. 매개변수는 `sub_group_size`의 버킷으로 그룹화되며 각 버킷은 한 번에 하나씩 업데이트됩니다. NVMe 오프로드와 함께 사용하는 경우 `sub_group_size`는 최적화 단계 중 모델 상태가 CPU 메모리로 이동하는 시점을 결정합니다. 이렇게 하면 매우 큰 모델의 CPU 메모리 부족을 방지할 수 있습니다. NVMe 오프로드를 사용하지 않는 경우 `sub_group_size`를 기본값으로 둘 수 있지만, 사용하는 경우 변경하는 것이 좋습니다:
+
+ 1. 옵티마이저 단계에서 OOM 오류가 발생합니다. 이 경우, 임시 버퍼의 메모리 사용량을 줄이려면 `sub_group_size`를 줄이세요.
+ 2. 옵티마이저 단계에서 시간이 너무 오래 걸립니다. 이 경우 데이터 버퍼 증가로 인한 대역폭 사용률을 개선하기 위해 `sub_group_size`를 늘리세요.
+
+* `reduce_bucket_size`, `stage3_prefetch_bucket_size`, `stage3_param_persistence_threshold`는 모델의 숨겨진 크기에 따라 달라집니다. 이 값들을 `auto`으로 설정하고 [`Trainer`]가 자동으로 값을 할당하도록 허용하는 것이 좋습니다.
+
+```yml
+{
+ "zero_optimization": {
+ "stage": 3,
+ "offload_optimizer": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "offload_param": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "overlap_comm": true,
+ "contiguous_gradients": true,
+ "sub_group_size": 1e9,
+ "reduce_bucket_size": "auto",
+ "stage3_prefetch_bucket_size": "auto",
+ "stage3_param_persistence_threshold": "auto",
+ "stage3_max_live_parameters": 1e9,
+ "stage3_max_reuse_distance": 1e9,
+ "stage3_gather_16bit_weights_on_model_save": true
+ }
+}
+```
+
+[`deepspeed.zero.Init`](https://deepspeed.readthedocs.io/en/latest/zero3.html#deepspeed.zero.Init) 컨텍스트 매니저를 사용하면 모델을 더 빠르게 초기화할 수 있습니다:
+
+```py
+from transformers import T5ForConditionalGeneration, T5Config
+import deepspeed
+
+with deepspeed.zero.Init():
+ config = T5Config.from_pretrained("google-t5/t5-small")
+ model = T5ForConditionalGeneration(config)
+```
+
+사전 학습된 모델의 경우, 딥스피드 구성 파일에 `is_deepspeed_zero3_enabled: true`가 [`TrainingArguments`]에 설정되어 있어야 하며, ZeRO 구성이 활성화되어 있어야 합니다. 훈련된 모델 [`~PreTrainedModel.from_pretrained`]을 호출하기 **전에** [`TrainingArguments`] 객체를 생성해야 합니다.
+
+```py
+from transformers import AutoModel, Trainer, TrainingArguments
+
+training_args = TrainingArguments(..., deepspeed=ds_config)
+model = AutoModel.from_pretrained("google-t5/t5-small")
+trainer = Trainer(model=model, args=training_args, ...)
+```
+
+fp16 가중치가 단일 GPU에 맞지 않는 경우 ZeRO-3이 필요합니다. fp16 가중치를 로드할 수 있는 경우, [`~PreTrainedModel.from_pretrained`]에 `torch_dtype=torch.float16`을 지정해야 합니다.
+
+ZeRO-3의 또 다른 고려 사항은 여러 개의 GPU를 사용하는 경우 현재 실행 중인 레이어의 매개변수가 아닌 한 단일 GPU에 모든 매개변수가 없다는 것입니다. 사전 훈련된 모델 가중치를 [`~PreTrainedModel.from_pretrained`]에 로드하는 등 모든 레이어의 모든 매개변수에 한 번에 액세스하려면 한 번에 하나의 레이어를 로드하고 즉시 모든 GPU에 파티셔닝합니다. 이는 매우 큰 모델의 경우 메모리 제한으로 인해 하나의 GPU에 가중치를 로드한 다음 다른 GPU에 분산할 수 없기 때문입니다.
+
+다음과 같이 보이는 모델 매개변수 가중치(여기서 `tensor([1.])`) 또는 매개변수 크기가 더 큰 다차원 형태 대신 1인 경우, 이는 매개변수가 분할되어 있으며 이것이 ZeRO-3 플레이스홀더인 것을 의미합니다.
+
+```py
+tensor([1.0], device="cuda:0", dtype=torch.float16, requires_grad=True)
+```
+
+
+
+ZeRO-3로 대규모 모델을 초기화하고 매개변수에 액세스하는 방법에 대한 자세한 내용은 [Constructing Massive Models](https://deepspeed.readthedocs.io/en/latest/zero3.html#constructing-massive-models) 및 [Gathering Parameters](https://deepspeed.readthedocs.io/en/latest/zero3.html#gathering-parameters) 가이드를 참조하세요.
+
+
+
+
+
+
+### NVMe 설정[[nvme-configuration]]
+
+[ZeRO-Infinity](https://hf.co/papers/2104.07857)를 사용하면 모델 상태를 CPU 및/또는 NVMe로 오프로드하여 더 많은 메모리를 절약할 수 있습니다. 스마트 파티셔닝 및 타일링 알고리즘을 통해 각 GPU는 오프로딩 중에 매우 적은 양의 데이터를 주고받을 수 있으므로 최신 NVMe는 훈련 프로세스에 사용할 수 있는 것보다 훨씬 더 큰 총 메모리 풀에 맞출 수 있습니다. ZeRO-Infinity에는 ZeRO-3가 필요합니다.
+
+사용 가능한 CPU 및/또는 NVMe 메모리에 따라 [옵티마이저](https://www.deepspeed.ai/docs/config-json/#optimizer-offloading)와 [매개변수](https://www.deepspeed.ai/docs/config-json/#parameter-offloading) 중 하나만 오프로드하거나 아무것도 오프로드하지 않을 수 있습니다. 또한 일반 하드 드라이브나 솔리드 스테이트 드라이브에서도 작동하지만 속도가 현저히 느려지므로 `nvme_path`가 NVMe 장치를 가리키고 있는지 확인해야 합니다. 최신 NVMe를 사용하면 읽기 작업의 경우 최대 3.5GB/s, 쓰기 작업의 경우 최대 3GB/s의 전송 속도를 기대할 수 있습니다. 마지막으로, 트레이닝 설정에서 [벤치마크 실행하기](https://github.com/microsoft/DeepSpeed/issues/998)을 통해 최적의 'aio' 구성을 결정합니다.
+
+아래 예제 ZeRO-3/Infinity 구성 파일은 대부분의 매개변수 값을 `auto`으로 설정하고 있지만, 수동으로 값을 추가할 수도 있습니다.
+
+```yml
+{
+ "fp16": {
+ "enabled": "auto",
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ },
+
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "betas": "auto",
+ "eps": "auto",
+ "weight_decay": "auto"
+ }
+ },
+
+ "scheduler": {
+ "type": "WarmupLR",
+ "params": {
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto"
+ }
+ },
+
+ "zero_optimization": {
+ "stage": 3,
+ "offload_optimizer": {
+ "device": "nvme",
+ "nvme_path": "/local_nvme",
+ "pin_memory": true,
+ "buffer_count": 4,
+ "fast_init": false
+ },
+ "offload_param": {
+ "device": "nvme",
+ "nvme_path": "/local_nvme",
+ "pin_memory": true,
+ "buffer_count": 5,
+ "buffer_size": 1e8,
+ "max_in_cpu": 1e9
+ },
+ "aio": {
+ "block_size": 262144,
+ "queue_depth": 32,
+ "thread_count": 1,
+ "single_submit": false,
+ "overlap_events": true
+ },
+ "overlap_comm": true,
+ "contiguous_gradients": true,
+ "sub_group_size": 1e9,
+ "reduce_bucket_size": "auto",
+ "stage3_prefetch_bucket_size": "auto",
+ "stage3_param_persistence_threshold": "auto",
+ "stage3_max_live_parameters": 1e9,
+ "stage3_max_reuse_distance": 1e9,
+ "stage3_gather_16bit_weights_on_model_save": true
+ },
+
+ "gradient_accumulation_steps": "auto",
+ "gradient_clipping": "auto",
+ "steps_per_print": 2000,
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "wall_clock_breakdown": false
+}
+```
+
+## DeepSpeed 구성[[deepspeed-features]]
+
+이 섹션에서 간략하게 설명하는 몇 가지 중요한 매개변수를 DeepSpeed 구성 파일에 지정할 수 있습니다.
+
+### 활성화/그레이디언트 체크포인팅[[activationgradient-checkpointing]]
+
+활성화 및 그레이디언트 체크포인팅은 속도를 더 많은 GPU 메모리와 교환하여 GPU 메모리가 부족한 상황을 극복하거나 배치 크기를 늘려 성능을 향상시킬 수 있습니다. 이 기능을 활성화하려면 다음과 같이 하세요:
+
+1. 허깅 페이스 모델의 경우, [`Trainer`]에서 `model.gradient_checkpointing_enable()` 또는 `--gradient_checkpointing`을 설정합니다.
+2. 허깅 페이스가 아닌 모델의 경우, 딥스피드 [Activation Checkpointing API](https://deepspeed.readthedocs.io/en/latest/activation-checkpointing.html)를 사용합니다. 트랜스포머 모델링 코드를 대체하고 `torch.utils.checkpoint`를 DeepSpeed API로 대체할 수도 있습니다. 이 접근 방식은 순방향 활성화를 다시 계산하는 대신 CPU 메모리로 오프로드할 수 있으므로 더 유연합니다.
+
+### 옵티마이저와 스케줄러[[optimizer-and-scheduler]]
+
+`offload_optimizer`를 활성화하지 않는 한 DeepSpeed와 트랜스포머 옵티마이저 및 스케줄러를 혼합하여 사용할 수 있습니다. `offload_optimizer`를 활성화하면 CPU와 GPU 구현이 모두 있는 경우 DeepSpeed가 아닌 최적화기(LAMB 제외)를 사용할 수 있습니다.
+
+
+
+구성 파일의 최적화 프로그램 및 스케줄러 매개변수는 명령줄에서 설정할 수 있으므로 오류를 찾기 어렵지 않습니다. 예를 들어 학습 속도가 다른 곳에서 다른 값으로 설정된 경우 명령줄에서 이를 재정의할 수 있습니다. 최적화 프로그램 및 스케줄러 매개변수 외에도 [`Trainer`] 명령줄 인수가 DeepSpeed 구성과 일치하는지 확인해야 합니다.
+
+
+
+
+
+
+DeepSpeed는 여러 [옵티마이저](https://www.deepspeed.ai/docs/config-json/#optimizer-parameters)를 제공하지만(Adam, AdamW, OneBitAdam 및 LAMB) PyTorch에서 다른 옵티마이저를 가져올 수도 있습니다. 설정에서 옵티마이저를 구성하지 않으면 [`Trainer`]가 자동으로 AdamW를 선택하고 명령줄에서 제공된 값 또는 기본값을 사용합니다: `lr`, `adam_beta1`, `adam_beta2`, `adam_epsilon`, `weight_decay`.
+
+매개변수를 `"auto"`으로 설정하거나 원하는 값을 직접 수동으로 입력할 수 있습니다.
+
+```yaml
+{
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "betas": "auto",
+ "eps": "auto",
+ "weight_decay": "auto"
+ }
+ }
+}
+```
+
+최상위 구성에 다음을 추가하여 지원되지 않는 옵티마이저를 사용할 수도 있습니다.
+
+```yaml
+{
+ "zero_allow_untested_optimizer": true
+}
+```
+
+DeepSpeed==0.8.3부터 오프로드를 사용하려면 오프로드가 DeepSpeed의 CPU Adam 옵티마이저에서 가장 잘 작동하므로 최상위 수준 구성에 다음 사항을 추가해야 합니다.
+
+```yaml
+{
+ "zero_force_ds_cpu_optimizer": false
+}
+```
+
+
+
+
+DeepSpeed는 LRRangeTest, OneCycle, WarmupLR 및 WarmupDecayLR learning rate[schedulers](https://www.deepspeed.ai/docs/config-json/#scheduler-parameters)를 지원합니다.
+
+트랜스포머와 DeepSpeed는 동일한 두 가지 스케줄러를 제공합니다:
+
+* WarmupLR은 Transformers의 `--lr_scheduler_type constant_warmup`과 동일합니다.
+* WarmupDecayLR은 Transformers의 `--lr_scheduler_type linear`와 동일합니다(Transformers에서 사용되는 기본 스케줄러입니다).
+
+설정에서 스케줄러를 구성하지 않으면[`Trainer`]는 자동으로 WarmupDecayLR을 선택하고 명령줄에서 제공된 값 또는 기본값을 사용합니다: `warmup_min_lr`, `warmup_max_lr`, `warmup_num_steps`, `total_num_steps` (`max_steps`가 제공되지 않으면 런타임 중에 자동으로 계산됨).
+
+매개변수를 `"auto"`으로 설정하거나 원하는 값을 직접 수동으로 입력할 수 있습니다.
+
+```yaml
+{
+ "scheduler": {
+ "type": "WarmupDecayLR",
+ "params": {
+ "total_num_steps": "auto",
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto"
+ }
+ }
+}
+```
+
+
+
+
+### 정밀도[[precision]]
+
+DeepSpeed는 fp32, fp16 및 bf16 혼합 정밀도를 지원합니다.
+
+
+
+
+모델이 혼합 정밀도로 사전 학습되지 않은 경우와 같이 혼합 정밀도로 잘 작동하지 않는 경우 NaN 손실을 유발할 수 있는 오버플로 또는 언더플로 문제가 발생할 수 있습니다. 이러한 경우에는 기본 fp16 모드를 명시적으로 비활성화하여 전체 fp32 정밀도를 사용해야 합니다.
+
+```yaml
+{
+ "fp16": {
+ "enabled": false
+ }
+}
+```
+
+Ampere GPU 및 PyTorch 1.7 이상의 경우 일부 연산에 대해 더 효율적인 [tf32](https://pytorch.org/docs/stable/notes/cuda.html#tensorfloat-32-tf32-on-ampere-devices) 형식으로 자동 전환되지만 결과는 여전히 fp32로 표시됩니다. [`Trainer`]에서 `--tf32`를 설정하여 활성화하고 `--tf32 0` 또는 `--no_tf32`를 비활성화하면 제어할 수 있습니다.
+
+
+
+
+PyTorch AMP와 같은 fp16 혼합 정밀도를 구성하면 메모리 사용량이 줄어들고 훈련 속도가 빨라집니다.[`Trainer`]는 `args.fp16_backend` 값에 따라 fp16을 자동으로 활성화 또는 비활성화하며, 나머지 구성은 사용자가 설정할 수 있습니다. 명령줄에서 다음 인수를 전달하면 fp16이 활성화됩니다: `fp16`, `--fp16_backend amp` 또는 `--fp16_full_eval`.
+
+```yaml
+{
+ "fp16": {
+ "enabled": "auto",
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ }
+}
+```
+
+추가 딥스피드 fp16 훈련 옵션은 [fp16 훈련 옵션](https://www.deepspeed.ai/docs/config-json/#fp16-training-options) 참조를 참조하세요.
+
+Apex와 같은 fp16 혼합 정밀도를 구성하려면 아래 그림과 같이 `"auto"` 또는 직접 값을 설정합니다.[`Trainer`]는 `args.fp16_backend` 및 `args.fp16_opt_level`의 값에 따라 `amp`를 자동으로 구성합니다. 다음 인수를 전달하면 명령줄에서 활성화할 수도 있습니다: `fp16`, `--fp16_backend apex` 또는 `--fp16_opt_level 01`.
+
+```yaml
+{
+ "amp": {
+ "enabled": "auto",
+ "opt_level": "auto"
+ }
+}
+```
+
+
+
+
+bf16을 사용하려면 DeepSpeed==0.6.0 이상이 필요합니다. bf16은 fp32와 동적 범위가 동일하며 손실 스케일링이 필요하지 않습니다. 그러나 [gradient accumulation](#gradient-accumulation)을 bf16과 함께 사용하면 이 형식의 낮은 정밀도로 인해 손실이 발생할 수 있으므로 원하지 않는 그레이디언트가 bf16에 누적될 수 있습니다.
+
+bf16은 설정 파일에서 설정하거나 다음 인수를 전달하면 명령줄에서 활성화할 수 있습니다: `--bf16` 또는 `--bf16_full_eval`.
+
+```yaml
+{
+ "bf16": {
+ "enabled": "auto"
+ }
+}
+```
+
+
+
+
+### 배치 크기[[batch-size]]
+
+배치 크기는 자동으로 구성하거나 명시적으로 설정할 수 있습니다. `"auto"` 옵션을 사용하도록 선택하면 [`Trainer`]는 `train_micro_batch_size_per_gpu`를 args.`per_device_train_batch_size`의 값으로, `train_batch_size`를 `args.world_size * args.per_device_train_batch_size * args.gradient_accumulation_steps`로 설정합니다.
+
+```yaml
+{
+ "train_micro_batch_size_per_gpu": "auto",
+ "train_batch_size": "auto"
+}
+```
+
+### 그레이디언트 누적[[gradient-accumulation]]
+
+그레이디언트 누적을 자동으로 구성하거나 명시적으로 설정할 수 있습니다. `"auto"` 옵션을 사용하도록 선택하면 [`Trainer`]가 `args.gradient_accumulation_steps`의 값으로 설정합니다.
+
+```yaml
+{
+ "gradient_accumulation_steps": "auto"
+}
+
+```
+
+### 그레이디언트 클리핑[[gradient-clipping]]
+
+그레이디언트 클리핑은 자동으로 구성하거나 명시적으로 설정할 수 있습니다. `"auto"` 옵션을 사용하도록 선택하면 [`Trainer`]가 `args.max_grad_norm`의 값으로 설정합니다.
+
+```yaml
+{
+ "gradient_clipping": "auto"
+}
+```
+
+### 통신 데이터 유형(Communication data type)[[communication-data-type]]
+
+축소, 수집 및 분산 작업과 같은 통신 집합체의 경우 별도의 데이터 유형이 사용됩니다.
+
+모든 수집 및 분산 작업은 데이터와 동일한 데이터 유형으로 수행됩니다. 예를 들어 bf16으로 훈련하는 경우, 수집은 비손실 연산이므로 데이터도 bf16으로 수집됩니다.
+
+예를 들어 그레이디언트가 여러 GPU에 걸쳐 평균화되는 경우와 같이 감소 연산은 손실이 발생합니다. 통신이 fp16 또는 bf16으로 수행되는 경우, 낮은 정밀도로 여러 숫자를 더하면 정확하지 않기 때문에 손실이 발생할 가능성이 더 높습니다. 특히 fp16보다 정밀도가 낮은 bf16의 경우 더욱 그렇습니다. 이러한 이유로 기울기를 평균화할 때 손실이 최소화되므로 감소 연산에는 fp16이 기본값으로 사용됩니다.
+
+통신 데이터 유형은 설정 파일에서 `communication_data_type` 매개변수를 설정하여 선택할 수 있습니다. 예를 들어, fp32를 선택하면 약간의 오버헤드가 추가되지만 감소 연산이 fp32에 누적되고 준비가 되면 훈련 중인 반정밀 dtype으로 다운캐스트됩니다.
+
+```yaml
+{
+ "communication_data_type": "fp32"
+}
+```
+
+## 모델 배포[[deployment]]
+
+[torchrun](https://pytorch.org/docs/stable/elastic/run.html), `deepspeed` 런처 또는 [Accelerate](https://huggingface.co/docs/accelerate/basic_tutorials/launch#using-accelerate-launch) 등 다양한 런처를 통해 DeepSpeed를 배포할 수 있습니다. 배포하려면 [`Trainer`] 명령줄에 `--deepspeed ds_config.json`을 추가합니다. 필요한 명령줄 인수를 코드에 추가하려면 DeepSpeed의 [`add_config_arguments`](https://deepspeed.readthedocs.io/en/latest/initialize.html#argument-parsing) 유틸리티를 사용하는 것이 좋습니다.
+
+이 가이드에서는 다양한 트레이닝 설정에 대해 `deepspeed` 런처로 DeepSpeed를 배포하는 방법을 보여드립니다. 보다 실용적인 사용 예제는 이 [post](https://github.com/huggingface/transformers/issues/8771#issuecomment-759248400)에서 확인할 수 있습니다.
+
+
+
+
+여러 GPU에 DeepSpeed를 배포하려면 `--num_gpus` 매개변수를 추가하세요. 사용 가능한 모든 GPU를 사용하려는 경우 `--num_gpus`를 추가할 필요가 없습니다. 아래 예제에서는 2개의 GPU를 사용합니다.
+
+```bash
+deepspeed --num_gpus=2 examples/pytorch/translation/run_translation.py \
+--deepspeed tests/deepspeed/ds_config_zero3.json \
+--model_name_or_path google-t5/t5-small --per_device_train_batch_size 1 \
+--output_dir output_dir --overwrite_output_dir --fp16 \
+--do_train --max_train_samples 500 --num_train_epochs 1 \
+--dataset_name wmt16 --dataset_config "ro-en" \
+--source_lang en --target_lang ro
+```
+
+
+
+
+단일 GPU에 DeepSpeed를 배포하려면 `--num_gpus` 매개변수를 추가하세요. GPU가 1개만 있는 경우 이 값을 명시적으로 설정할 필요는 없습니다. DeepSpeed는 지정된 노드에서 볼 수 있는 모든 GPU를 배포하므로 이 값을 명시적으로 설정할 필요는 없습니다.
+
+```bash
+deepspeed --num_gpus=1 examples/pytorch/translation/run_translation.py \
+--deepspeed tests/deepspeed/ds_config_zero2.json \
+--model_name_or_path google-t5/t5-small --per_device_train_batch_size 1 \
+--output_dir output_dir --overwrite_output_dir --fp16 \
+--do_train --max_train_samples 500 --num_train_epochs 1 \
+--dataset_name wmt16 --dataset_config "ro-en" \
+--source_lang en --target_lang ro
+```
+
+DeepSpeed는 단 하나의 GPU로도 여전히 유용합니다:
+
+1. 일부 계산과 메모리를 CPU로 오프로드하여 더 큰 배치 크기를 사용하거나 일반적으로 맞지 않는 매우 큰 모델을 맞추기 위해 모델에 더 많은 GPU 리소스를 사용할 수 있도록 합니다.
+2. 스마트 GPU 메모리 관리 시스템으로 메모리 조각화를 최소화하여 더 큰 모델과 데이터 배치에 맞출 수 있습니다.
+
+
+
+단일 GPU에서 더 나은 성능을 얻으려면 [ZeRO-2](#zero-configuration) 구성 파일에서 `allgather_bucket_size` 및 `reduce_bucket_size` 값을 2e8로 설정하세요.
+
+
+
+
+
+
+### 다중 노드 환경에서의 모델 배포[[multi-node-deployment]]
+
+노드는 워크로드를 실행하기 위한 하나 이상의 GPU입니다. 더 강력한 설정은 멀티 노드 설정으로, `deepspeed` 런처로 실행할 수 있습니다. 이 가이드에서는 각각 8개의 GPU가 있는 두 개의 노드가 있다고 가정해 보겠습니다. 첫 번째 노드는 `ssh hostname1`로, 두 번째 노드는 `ssh hostname2`로 접속할 수 있습니다. 두 노드 모두 비밀번호 없이 ssh를 통해 로컬로 서로 통신할 수 있어야 합니다.
+
+기본적으로 DeepSpeed는 멀티노드 환경에서 공유 저장소를 사용할 것으로 예상합니다. 그렇지 않고 각 노드가 로컬 파일 시스템만 볼 수 있는 경우, 공유 파일 시스템에 대한 액세스 없이 로딩할 수 있도록 [`checkpoint`](https://www.deepspeed.ai/docs/config-json/#checkpoint-options)를 포함하도록 구성 파일을 조정해야 합니다:
+
+```yaml
+{
+ "checkpoint": {
+ "use_node_local_storage": true
+ }
+}
+```
+
+[`Trainer`]의 ``--save_on_each_node` 인수를 사용하여 위의 `checkpoint`를 구성에 자동으로 추가할 수도 있습니다.
+
+
+
+
+[torchrun](https://pytorch.org/docs/stable/elastic/run.html)의 경우, 각 노드에 ssh로 접속한 후 두 노드 모두에서 다음 명령을 실행해야 합니다. 런처는 두 노드가 동기화될 때까지 기다렸다가 트레이닝을 시작합니다.
+
+```bash
+torchrun --nproc_per_node=8 --nnode=2 --node_rank=0 --master_addr=hostname1 \
+--master_port=9901 your_program.py --deepspeed ds_config.json
+```
+
+
+
+
+`deepspeed` 런처의 경우, 먼저 `hostfile`을 생성합니다.
+
+```bash
+hostname1 slots=8
+hostname2 slots=8
+```
+
+그런 다음 다음 명령어로 트레이닝을 시작할 수 있습니다. `deepspeed` 런처는 두 노드에서 동시에 명령을 자동으로 실행합니다.
+
+```bash
+deepspeed --num_gpus 8 --num_nodes 2 --hostfile hostfile --master_addr hostname1 --master_port=9901 \
+your_program.py --deepspeed ds_config.json
+```
+
+다중 노드 컴퓨팅 리소스 구성에 대한 자세한 내용은 [Resource Configuration (multi-node)](https://www.deepspeed.ai/getting-started/#resource-configuration-multi-node) 가이드를 참조하세요.
+
+
+
+
+### SLURM[[slurm]]
+
+SLURM 환경에서는 특정 SLURM 환경에 맞게 SLURM 스크립트를 조정해야 합니다.SLURM 스크립트 예시는 다음과 같습니다:
+
+```bash
+#SBATCH --job-name=test-nodes # 작업 이름
+#SBATCH --nodes=2 # 노드 수
+#SBATCH --ntasks-per-node=1 # 중요 - 노드당 분산 작업 1개!
+#SBATCH --cpus-per-task=10 # 작업당 CPU 코어 수
+#SBATCH --gres=gpu:8 # gpu 수
+#SBATCH --time 20:00:00 # 최대 실행 시간 (HH:MM:SS)
+#SBATCH --output=%x-%j.out # 출력 파일 이름
+
+export GPUS_PER_NODE=8
+export MASTER_ADDR=$(scontrol show hostnames $SLURM_JOB_NODELIST | head -n 1)
+export MASTER_PORT=9901
+
+srun --jobid $SLURM_JOBID bash -c 'python -m torch.distributed.run \
+ --nproc_per_node $GPUS_PER_NODE --nnodes $SLURM_NNODES --node_rank $SLURM_PROCID \
+ --master_addr $MASTER_ADDR --master_port $MASTER_PORT \
+your_program.py --deepspeed ds_config.json'
+```
+
+그런 다음 모든 노드에서 동시에 학습을 시작하는 다음 명령을 사용하여 다중 노드 배포를 예약할 수 있습니다.
+
+```bash
+sbatch launch.slurm
+```
+
+### 노트북[[notebook]]
+
+`deepspeed` 런처는 노트북에서의 배포를 지원하지 않으므로 분산 환경을 에뮬레이션해야 합니다. 하지만 이는 1개의 GPU에서만 작동합니다. 1개 이상의 GPU를 사용하려면 딥스피드가 작동할 수 있는 다중 프로세스 환경을 사용해야 합니다. 즉, 여기에 표시된 것처럼 에뮬레이션할 수 없는 `deepspeed` 런처를 사용해야 합니다.
+
+```py
+# DeepSpeed는 단일 프로세스만 사용하더라도 분산 환경을 필요로 합니다.
+# 이 코드로 분산 환경을 모방합니다.
+import os
+
+os.environ["MASTER_ADDR"] = "localhost"
+os.environ["MASTER_PORT"] = "9994" # RuntimeError: Address already in use 오류 발생 시 수정
+os.environ["RANK"] = "0"
+os.environ["LOCAL_RANK"] = "0"
+os.environ["WORLD_SIZE"] = "1"
+
+# 이제 평소와 같이 진행하되, DeepSpeed 설정 파일을 전달합니다.
+training_args = TrainingArguments(..., deepspeed="ds_config_zero3.json")
+trainer = Trainer(...)
+trainer.train()
+```
+
+현재 디렉터리의 노트북에 구성 파일을 즉석에서 만들고 싶다면 전용 셀을 만들 수 있습니다.
+
+```py
+%%bash
+cat <<'EOT' > ds_config_zero3.json
+{
+ "fp16": {
+ "enabled": "auto",
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ },
+
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "betas": "auto",
+ "eps": "auto",
+ "weight_decay": "auto"
+ }
+ },
+
+ "scheduler": {
+ "type": "WarmupLR",
+ "params": {
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto"
+ }
+ },
+
+ "zero_optimization": {
+ "stage": 3,
+ "offload_optimizer": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "offload_param": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "overlap_comm": true,
+ "contiguous_gradients": true,
+ "sub_group_size": 1e9,
+ "reduce_bucket_size": "auto",
+ "stage3_prefetch_bucket_size": "auto",
+ "stage3_param_persistence_threshold": "auto",
+ "stage3_max_live_parameters": 1e9,
+ "stage3_max_reuse_distance": 1e9,
+ "stage3_gather_16bit_weights_on_model_save": true
+ },
+
+ "gradient_accumulation_steps": "auto",
+ "gradient_clipping": "auto",
+ "steps_per_print": 2000,
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "wall_clock_breakdown": false
+}
+EOT
+```
+
+트레이닝 스크립트가 노트북 셀이 아닌 파일에 있는 경우, 노트북 셀의 셸에서 `deepspeed`를 정상적으로 실행할 수 있습니다. 예를 들어 `run_translation.py`를 시작하려면 다음과 같이 하세요.:
+
+```py
+!git clone https://github.com/huggingface/transformers
+!cd transformers; deepspeed examples/pytorch/translation/run_translation.py ...
+```
+
+또한 `%%bash` 매직을 사용하여 여러 줄의 코드를 작성하여 셸 프로그램을 실행할 수도 있지만 교육이 완료될 때까지 로그를 볼 수 없습니다. `%%bash` 매직으로 분산 환경을 에뮬레이션할 필요는 없습니다.
+
+```py
+%%bash
+
+git clone https://github.com/huggingface/transformers
+cd transformers
+deepspeed examples/pytorch/translation/run_translation.py ...
+```
+
+## 모델 가중치 저장하기[[save-model-weights]]
+
+딥스피드는 기본 고정밀 fp32 가중치를 사용자 지정 체크포인트 최적화 파일(glob 패턴은 `global_step*/*optim_states.pt`처럼 보입니다)에 저장하고 일반 체크포인트 아래에 저장합니다.
+
+
+
+
+ZeRO-2로 훈련된 모델은 pytorch_model.bin 가중치를 fp16에 저장합니다. ZeRO-3으로 훈련된 모델의 모델 가중치를 fp16에 저장하려면 모델 가중치가 여러 GPU에 분할되어 있으므로 `“stage3_gather_16bit_weights_on_model_save”: true`를 설정해야 합니다. 그렇지 않으면 [`Trainer`]가 가중치를 fp16에 저장하지 않고 pytorch_model.bin 파일을 생성하지 않습니다. 이는 DeepSpeed의 state_dict에 실제 가중치 대신 플레이스홀더가 포함되어 있어 이를 로드할 수 없기 때문입니다.
+
+```yaml
+{
+ "zero_optimization": {
+ "stage3_gather_16bit_weights_on_model_save": true
+ }
+}
+```
+
+
+
+
+전체 정밀 가중치는 많은 메모리가 필요할 수 있으므로 트레이닝 중에 저장해서는 안 됩니다. 일반적으로 훈련이 완료된 후 오프라인으로 fp32 가중치를 저장하는 것이 가장 좋습니다. 그러나 여유 CPU 메모리가 많은 경우 훈련 중에 fp32 가중치를 저장할 수 있습니다. 이 섹션에서는 온라인과 오프라인 방식을 모두 다룹니다.
+
+### 온라인 환경[[online]]
+
+다음과 같이 최신 체크포인트를 로드하려면 체크포인트를 하나 이상 저장해야 합니다:
+
+```py
+from transformers.trainer_utils import get_last_checkpoint
+from deepspeed.utils.zero_to_fp32 import load_state_dict_from_zero_checkpoint
+
+checkpoint_dir = get_last_checkpoint(trainer.args.output_dir)
+fp32_model = load_state_dict_from_zero_checkpoint(trainer.model, checkpoint_dir)
+```
+
+`--load_best_model_at_end` 매개변수를 활성화하여 [`TrainingArguments`]에서 최적의 체크포인트를 추적하는 경우, 먼저 학습을 완료하고 최종 모델을 명시적으로 저장할 수 있습니다. 그런 다음 아래와 같이 다시 로드할 수 있습니다:
+
+```py
+from deepspeed.utils.zero_to_fp32 import load_state_dict_from_zero_checkpoint
+
+checkpoint_dir = os.path.join(trainer.args.output_dir, "checkpoint-final")
+trainer.deepspeed.save_checkpoint(checkpoint_dir)
+fp32_model = load_state_dict_from_zero_checkpoint(trainer.model, checkpoint_dir)
+```
+
+
+
+`load_state_dict_from_zero_checkpoint`가 실행되면 동일한 애플리케이션의 컨텍스트에서 모델을 더 이상 DeepSpeed에서 사용할 수 없습니다. `model.load_state_dict(state_dict)`는 모든 딥스피드 마법을 제거하므로 딥스피드 엔진을 다시 초기화해야 합니다. 이 기능은 훈련이 끝날 때만 사용하세요.
+
+
+
+fp32 가중치의 state_dict를 추출하여 로드할 수도 있습니다:
+
+```py
+from deepspeed.utils.zero_to_fp32 import get_fp32_state_dict_from_zero_checkpoint
+
+state_dict = get_fp32_state_dict_from_zero_checkpoint(checkpoint_dir) # cpu에 이미 존재함
+model = model.cpu()
+model.load_state_dict(state_dict)
+```
+
+### 오프라인 환경[[offline]]
+
+DeepSpeed는 언제든지 가중치를 추출할 수 있도록 체크포인트 폴더의 최상위 레벨에 zero_to_fp32.py 스크립트를 제공합니다. 이 스크립트는 독립형 스크립트로 구성 파일이나 [`Trainer`]가 필요하지 않습니다.
+
+예를 들어 체크포인트 폴더가 다음과 같은 경우입니다:
+
+```bash
+$ ls -l output_dir/checkpoint-1/
+-rw-rw-r-- 1 stas stas 1.4K Mar 27 20:42 config.json
+drwxrwxr-x 2 stas stas 4.0K Mar 25 19:52 global_step1/
+-rw-rw-r-- 1 stas stas 12 Mar 27 13:16 latest
+-rw-rw-r-- 1 stas stas 827K Mar 27 20:42 optimizer.pt
+-rw-rw-r-- 1 stas stas 231M Mar 27 20:42 pytorch_model.bin
+-rw-rw-r-- 1 stas stas 623 Mar 27 20:42 scheduler.pt
+-rw-rw-r-- 1 stas stas 1.8K Mar 27 20:42 special_tokens_map.json
+-rw-rw-r-- 1 stas stas 774K Mar 27 20:42 spiece.model
+-rw-rw-r-- 1 stas stas 1.9K Mar 27 20:42 tokenizer_config.json
+-rw-rw-r-- 1 stas stas 339 Mar 27 20:42 trainer_state.json
+-rw-rw-r-- 1 stas stas 2.3K Mar 27 20:42 training_args.bin
+-rwxrw-r-- 1 stas stas 5.5K Mar 27 13:16 zero_to_fp32.py*
+```
+
+딥스피드 체크포인트(ZeRO-2 또는 ZeRO-3) 하위 폴더 `global_step1`에서 fp32 가중치를 재구성하려면 다음 명령을 실행하여 여러 GPU의 전체 fp32 가중치를 단일 pytorch_model.bin 파일로 생성하고 통합합니다. 스크립트는 자동으로 체크포인트가 포함된 하위 폴더를 찾습니다.
+
+```py
+python zero_to_fp32.py . pytorch_model.bin
+```
+
+
+
+자세한 사용법은 `python zero_to_fp32.py -h`를 실행하세요. 이 스크립트에는 최종 fp32 가중치의 2배의 일반 RAM이 필요합니다.
+
+
+
+
+
+
+## ZeRO Inference[[zero-inference]]
+
+[ZeRO Inference](https://www.deepspeed.ai/2022/09/09/zero-inference.html)는 모델 가중치를 CPU 또는 NVMe 메모리에 배치하여 GPU에 부담을 주지 않으므로 GPU에서 대규모 모델을 사용하여 추론을 실행할 수 있습니다. 추론은 최적화 상태 및 그레이디언트에 많은 양의 메모리를 추가로 필요로 하지 않으므로 동일한 하드웨어에 훨씬 더 큰 배치 및/또는 시퀀스 길이를 맞출 수 있습니다.
+
+ZeRO Inference는 [ZeRO-3](#zero-configuration)와 동일한 구성 파일을 공유하며, ZeRO-2 및 ZeRO-1 구성은 추론에 아무런 이점을 제공하지 않으므로 작동하지 않습니다.
+
+ZeRO Inference를 실행하려면 일반적인 훈련 인수를 [`TrainingArguments`] 클래스에 전달하고 `--do_eval` 인수를 추가합니다.
+
+```bash
+deepspeed --num_gpus=2 your_program.py --do_eval --deepspeed ds_config.json
+```
+
+## Trainer 없이 DeepSpeed 사용하기[[non-trainer-deepspeed-integration]]
+
+DeepSpeed는 [`Trainer`] 클래스가 없는 트랜스포머에서도 작동합니다. 이는 [`~PreTrainedModel.from_pretrained`]를 호출할 때 ZeRO-3 매개변수를 수집하고 모델을 여러 GPU에 분할하는 작업만 처리하는 [`HfDeepSpeedConfig`]가 처리합니다.
+
+
+
+모든 것이 자동으로 처리되기를 원한다면, [`Trainer`]와 함께 DeepSpeed를 사용해 보세요! [DeepSpeed 문서](https://www.deepspeed.ai/)를 참조하여 설정 파일에서 매개변수 값을 수동으로 구성해야 합니다(`"auto"` 값은 사용할 수 없음).
+
+
+
+ZeRO-3를 효율적으로 배포하려면 모델 앞에 [`HfDeepSpeedConfig`] 객체를 인스턴스화하고 해당 객체를 유지해야 합니다:
+
+
+
+
+```py
+from transformers.integrations import HfDeepSpeedConfig
+from transformers import AutoModel
+import deepspeed
+
+ds_config = {...} # deepspeed 설정 객체 또는 파일 경로
+# Zero 3를 감지하기 위해 모델을 인스턴스화하기 전에 반드시 실행해야 합니다
+dschf = HfDeepSpeedConfig(ds_config) # 이 객체를 유지하세요.
+model = AutoModel.from_pretrained("openai-community/gpt2")
+engine = deepspeed.initialize(model=model, config_params=ds_config, ...)
+```
+
+
+
+
+[`HfDeepSpeedConfig`] is not required for ZeRO-1 or ZeRO-2.
+
+```py
+from transformers.integrations import HfDeepSpeedConfig
+from transformers import AutoModel, AutoConfig
+import deepspeed
+
+ds_config = {...} # deepspeed 설정 객체 또는 파일 경로
+# Zero 3를 감지하기 위해 모델을 인스턴스화하기 전에 반드시 실행해야 합니다
+dschf = HfDeepSpeedConfig(ds_config) # 이 객체를 유지하세요.
+config = AutoConfig.from_pretrained("openai-community/gpt2")
+model = AutoModel.from_config(config)
+engine = deepspeed.initialize(model=model, config_params=ds_config, ...)
+```
+
+
+
+
+### Trainer 없이 ZeRO Inference 사용하기[[non-trainer-zero-inference]]
+
+단일 GPU에 모델을 맞출 수 없는 경우 [`Trainer`]없이 ZeRO 추론을 실행하려면 추가 GPU를 사용하거나 CPU 메모리로 오프로드를 시도하세요. 여기서 이해해야 할 중요한 뉘앙스는 ZeRO가 설계된 방식에 따라 서로 다른 GPU에서 서로 다른 입력을 병렬로 처리할 수 있다는 것입니다.
+
+반드시 확인하세요:
+
+* GPU 메모리가 충분한 경우 CPU 오프로드를 비활성화합니다(속도가 느려지므로).
+* Ampere 이상의 GPU를 사용하는 경우 bf16을 활성화하면 속도가 빨라집니다. 이러한 GPU가 없는 경우 오버플로 오류가 발생할 수 있으므로 bf16으로 사전 학습된 모델(T5 모델)을 사용하지 않는 한 fp16을 활성화할 수 있습니다.
+
+단일 GPU에 맞지 않는 모델에서 [`Trainer`] 없이 ZeRO 추론을 실행하는 방법에 대한 더 나은 아이디어를 얻으려면 다음 스크립트를 살펴보시기 바랍니다.
+
+```py
+#!/usr/bin/env python
+
+# 이 스크립트는 단일 GPU에 모델을 맞출 수 없을 때 추론 모드에서 Deepspeed ZeRO를 사용하는 방법을 보여줍니다.
+#
+# 1. CPU 오프로드와 함께 1개의 GPU 사용
+# 2. 또는 여러 GPU 사용
+#
+# 먼저 deepspeed를 설치해야 합니다: pip install deepspeed
+#
+# 여기서는 약 15GB의 GPU RAM이 필요한 3B "bigscience/T0_3B" 모델을 사용합니다 - 따라서 1개의 큰 GPU나 2개의
+# 작은 GPU로 처리할 수 있습니다. 또는 1개의 작은 GPU와 많은 CPU 메모리로도 가능합니다.
+#
+# 약 50GB가 필요한 "bigscience/T0"와 같은 더 큰 모델을 사용하려면, 80GB GPU가 없는 한
+# 2-4개의 GPU가 필요할 것입니다. 그리고 여러 입력을 한 번에 처리하고 싶다면
+# 스크립트를 수정하여 더 많은 GPU를 처리할 수 있습니다.
+#
+# 제공된 deepspeed 설정은 CPU 메모리 오프로딩도 활성화하므로, 사용 가능한 CPU 메모리가 많고
+# 속도 저하를 감수할 수 있다면 일반적으로 단일 GPU에 맞지 않는 모델을 로드할 수 있을 것입니다.
+# GPU 메모리가 충분하다면 CPU로의 오프로드를 원하지 않을 때 프로그램이 더 빠르게 실행될 것입니다 - 그럴 때는 해당 섹션을 비활성화하세요.
+#
+# 1개의 GPU에 배포하려면:
+#
+# deepspeed --num_gpus 1 t0.py
+# 또는:
+# python -m torch.distributed.run --nproc_per_node=1 t0.py
+#
+# 2개의 GPU에 배포하려면:
+#
+# deepspeed --num_gpus 2 t0.py
+# 또는:
+# python -m torch.distributed.run --nproc_per_node=2 t0.py
+
+from transformers import AutoTokenizer, AutoConfig, AutoModelForSeq2SeqLM
+from transformers.integrations import HfDeepSpeedConfig
+import deepspeed
+import os
+import torch
+
+os.environ["TOKENIZERS_PARALLELISM"] = "false" # 토크나이저의 병렬 처리에 관한 경고를 피하기 위함입니다.
+
+# 분산 환경 설정
+local_rank = int(os.getenv("LOCAL_RANK", "0"))
+world_size = int(os.getenv("WORLD_SIZE", "1"))
+torch.cuda.set_device(local_rank)
+deepspeed.init_distributed()
+
+model_name = "bigscience/T0_3B"
+
+config = AutoConfig.from_pretrained(model_name)
+model_hidden_size = config.d_model
+
+# 배치 크기는 world_size로 나누어 떨어져야 하지만, world_size보다 클 수 있습니다
+train_batch_size = 1 * world_size
+
+# ds_config 참고사항
+#
+# - Ampere 이상의 GPU를 사용하는 경우 bf16을 활성화하세요 - 이는 혼합 정밀도로 실행되어
+# 더 빠를 것입니다.
+#
+# - 오래된 GPU의 경우 fp16을 활성화할 수 있지만, bf16으로 사전 훈련되지 않은 모델에서만 작동합니다 - 예를 들어
+# 모든 공식 t5 모델은 bf16으로 사전 훈련되었습니다
+#
+# - CPU 오프로드를 원하지 않는다면 offload_param.device를 "none"으로 설정하거나 `offload_param` 섹션을
+# 완전히 제거하세요
+#
+# - `offload_param`을 사용하는 경우, stage3_param_persistence_threshold를 수동으로 미세 조정하여
+# 어떤 매개변수가 GPU에 남아있어야 하는지 제어할 수 있습니다 - 값이 클수록 오프로드 크기가 작아집니다
+#
+# Deepspeed 설정에 대한 자세한 정보는 다음을 참조하세요
+# https://huggingface.co/docs/transformers/main/main_classes/deepspeed
+
+# 일관성을 위해 json과 동일한 형식을 유지하되, true/false에는 소문자를 사용합니다
+# fmt: off
+ds_config = {
+ "fp16": {
+ "enabled": False
+ },
+ "bf16": {
+ "enabled": False
+ },
+ "zero_optimization": {
+ "stage": 3,
+ "offload_param": {
+ "device": "cpu",
+ "pin_memory": True
+ },
+ "overlap_comm": True,
+ "contiguous_gradients": True,
+ "reduce_bucket_size": model_hidden_size * model_hidden_size,
+ "stage3_prefetch_bucket_size": 0.9 * model_hidden_size * model_hidden_size,
+ "stage3_param_persistence_threshold": 10 * model_hidden_size
+ },
+ "steps_per_print": 2000,
+ "train_batch_size": train_batch_size,
+ "train_micro_batch_size_per_gpu": 1,
+ "wall_clock_breakdown": False
+}
+# fmt: on
+
+# 다음 줄은 모델의 `from_pretrained` 메소드가 호출될 때
+# deepspeed.zero.Init를 사용하여 모델을 여러 GPU에 직접 분할하도록 transformers에 지시합니다.
+#
+# **이는 AutoModelForSeq2SeqLM.from_pretrained(model_name)로 모델을 로드하기 전에 실행되어야 합니다**
+#
+# 그렇지 않으면 모델이 먼저 정상적으로 로드된 후 포워드 시에만 분할되는데, 이는
+# 덜 효율적이며 CPU RAM이 부족할 경우 실패할 수 있습니다
+dschf = HfDeepSpeedConfig(ds_config) # 이 객체를 유지하세요
+
+# 이제 모델을 로드할 수 있습니다.
+model = AutoModelForSeq2SeqLM.from_pretrained(model_name)
+
+# Deepspeed ZeRO를 초기화하고 엔진 객체만 저장
+ds_engine = deepspeed.initialize(model=model, config_params=ds_config)[0]
+ds_engine.module.eval() # inference
+
+# Deepspeed ZeRO는 각 GPU에서 서로 관련 없는 입력을 처리할 수 있습니다. 따라서 2개의 GPU를 사용하면 한 번에 2개의 입력을 처리할 수 있습니다.
+# GPU를 더 많이 사용하는 경우 그에 맞게 조정하세요.
+
+# 물론 처리할 입력이 하나뿐이라면 두 GPU에 동일한 문자열을 전달해야 합니다.
+# GPU를 하나만 사용하는 경우에는 rank 0만 갖게 됩니다.
+rank = torch.distributed.get_rank()
+if rank == 0:
+ text_in = "Is this review positive or negative? Review: this is the best cast iron skillet you will ever buy"
+elif rank == 1:
+ text_in = "Is this review positive or negative? Review: this is the worst restaurant ever"
+
+tokenizer = AutoTokenizer.from_pretrained(model_name)
+inputs = tokenizer.encode(text_in, return_tensors="pt").to(device=local_rank)
+with torch.no_grad():
+ outputs = ds_engine.module.generate(inputs, synced_gpus=True)
+text_out = tokenizer.decode(outputs[0], skip_special_tokens=True)
+print(f"rank{rank}:\n in={text_in}\n out={text_out}")
+```
+
+스크립트를 t0.py로 저장하고 실행합니다:
+
+```bash
+$ deepspeed --num_gpus 2 t0.py
+rank0:
+ in=Is this review positive or negative? Review: this is the best cast iron skillet you will ever buy
+ out=Positive
+rank1:
+ in=Is this review positive or negative? Review: this is the worst restaurant ever
+ out=negative
+```
+
+이것은 매우 기본적인 예시이므로 사용 사례에 맞게 조정할 수 있습니다.
+
+### 생성[[generate]]
+
+생성에 ZeRO-3와 함께 여러 개의 GPU를 사용하려면 [`~GenerationMixin.generate`] 메서드에서 `synced_gpus=True`를 설정하여 GPU를 동기화해야 합니다. 그렇지 않으면 한 GPU가 다른 GPU보다 먼저 생성을 완료하면 나머지 GPU가 먼저 완료한 GPU로부터 가중치 샤드를 받지 못하여 전체 시스템이 중단됩니다.
+
+트랜스포머>=4.28의 경우, 생성 중에 여러 개의 GPU가 감지되면 `synced_gpus`가 자동으로 `True`로 설정됩니다.
+
+## 트러블슈팅[[troubleshoot]]
+
+문제가 발생하면 DeepSpeed가 문제의 원인이 아닌 경우가 많으므로(아주 명백하고 예외적으로 DeepSpeed 모듈을 볼 수 있는 경우가 아니라면) DeepSpeed가 문제의 원인인지 고려해야 합니다! 첫 번째 단계는 DeepSpeed 없이 설정을 다시 시도하고 문제가 지속되면 문제를 신고하는 것입니다. 문제가 핵심적인 DeepSpeed 문제이고 transformers와 관련이 없는 경우, [DeepSpeed 리포지토리](https://github.com/microsoft/DeepSpeed)에서 이슈를 개설하세요.
+
+transformers와 관련된 이슈를 개설할 때에는 다음 정보를 제공해 주세요:
+
+* 전체 DeepSpeed 구성 파일
+
+*[`Trainer`]의 명령줄 인수, 또는[`Trainer`] 설정을 직접 작성하는 경우[`TrainingArguments`] 인수(관련 없는 항목이 수십 개 있는 [`TrainingArguments`]는 덤프하지 마세요).
+
+* 다음 코드의 출력 결과:
+
+```bash
+python -c 'import torch; print(f"torch: {torch.__version__}")'
+python -c 'import transformers; print(f"transformers: {transformers.__version__}")'
+python -c 'import deepspeed; print(f"deepspeed: {deepspeed.__version__}")'
+```
+
+* 문제를 재현할 수 있는 Google Colab 노트북 링크
+
+* 불가능할 경우 기존 예제를 사용하여 문제를 재현할 수 있는 표준 및 사용자 지정이 아닌 데이터 집합을 사용할 수 있습니다.
+
+다음 섹션에서는 가장 일반적인 두 가지 문제를 해결하기 위한 가이드를 제공합니다.
+
+### DeepSpeed 프로세스가 시작 단계에서 종료되었을 경우[[deepspeed-process-killed-at-startup]]
+
+실행 중에 트레이스백 없이 DeepSpeed 프로세스가 종료되면 일반적으로 프로그램이 시스템보다 많은 CPU 메모리를 할당하려고 시도했거나 프로세스가 허용된 것보다 많은 CPU 메모리를 할당하려고 시도하여 OS 커널이 프로세스를 종료했음을 의미합니다. 이 경우 구성 파일에 `offload_optimizer`, `offload_param` 또는 둘 다 CPU로 오프로드하도록 구성되어 있는지 확인하세요.
+
+NVMe 및 ZeRO-3를 설정한 경우 NVMe로 오프로드를 실험해 보세요(모델의 메모리 요구 사항을 [확인](https://deepspeed.readthedocs.io/en/latest/memory.html)하세요).
+
+### NaN 손실[[nan-loss]]
+
+모델을 bf16으로 사전 훈련한 다음 fp16으로 사용하려고 할 때 NaN 손실이 발생하는 경우가 많습니다(특히 TPU 훈련 모델에 해당). 이 문제를 해결하려면 하드웨어가 이를 지원하는 경우(TPU, Ampere GPU 이상) fp32 또는 bf16을 사용하세요.
+
+다른 문제는 fp16 사용과 관련이 있을 수 있습니다. 예를 들어 이것이 fp16 구성인 경우입니다:
+
+```yaml
+{
+ "fp16": {
+ "enabled": "auto",
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ }
+}
+```
+
+로그에 다음과 같은 `OVERFLOW!` 메시지가 표시될 수 있습니다:
+
+```bash
+0%| | 0/189 [00:00
+
+# 🤗 Tokenizers 라이브러리의 토크나이저 사용하기[[use-tokenizers-from-tokenizers]]
+
+[`PreTrainedTokenizerFast`]는 [🤗 Tokenizers](https://huggingface.co/docs/tokenizers) 라이브러리에 기반합니다. 🤗 Tokenizers 라이브러리의 토크나이저는
+🤗 Transformers로 매우 간단하게 불러올 수 있습니다.
+
+구체적인 내용에 들어가기 전에, 몇 줄의 코드로 더미 토크나이저를 만들어 보겠습니다:
+
+```python
+>>> from tokenizers import Tokenizer
+>>> from tokenizers.models import BPE
+>>> from tokenizers.trainers import BpeTrainer
+>>> from tokenizers.pre_tokenizers import Whitespace
+
+>>> tokenizer = Tokenizer(BPE(unk_token="[UNK]"))
+>>> trainer = BpeTrainer(special_tokens=["[UNK]", "[CLS]", "[SEP]", "[PAD]", "[MASK]"])
+
+>>> tokenizer.pre_tokenizer = Whitespace()
+>>> files = [...]
+>>> tokenizer.train(files, trainer)
+```
+
+우리가 정의한 파일을 통해 이제 학습된 토크나이저를 갖게 되었습니다. 이 런타임에서 계속 사용하거나 JSON 파일로 저장하여 나중에 사용할 수 있습니다.
+
+## 토크나이저 객체로부터 직접 불러오기[[loading-directly-from-the-tokenizer-object]]
+
+🤗 Transformers 라이브러리에서 이 토크나이저 객체를 활용하는 방법을 살펴보겠습니다.
+[`PreTrainedTokenizerFast`] 클래스는 인스턴스화된 *토크나이저* 객체를 인수로 받아 쉽게 인스턴스화할 수 있습니다:
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_object=tokenizer)
+```
+
+이제 `fast_tokenizer` 객체는 🤗 Transformers 토크나이저에서 공유하는 모든 메소드와 함께 사용할 수 있습니다! 자세한 내용은 [토크나이저 페이지](main_classes/tokenizer)를 참조하세요.
+
+## JSON 파일에서 불러오기[[loading-from-a-JSON-file]]
+
+
+
+JSON 파일에서 토크나이저를 불러오기 위해, 먼저 토크나이저를 저장해 보겠습니다:
+
+```python
+>>> tokenizer.save("tokenizer.json")
+```
+
+JSON 파일을 저장한 경로는 `tokenizer_file` 매개변수를 사용하여 [`PreTrainedTokenizerFast`] 초기화 메소드에 전달할 수 있습니다:
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_file="tokenizer.json")
+```
+
+이제 `fast_tokenizer` 객체는 🤗 Transformers 토크나이저에서 공유하는 모든 메소드와 함께 사용할 수 있습니다! 자세한 내용은 [토크나이저 페이지](main_classes/tokenizer)를 참조하세요.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/fsdp.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/fsdp.md
new file mode 100644
index 0000000000000000000000000000000000000000..bab1fda71b4ed10542aea99837bbd06154abd888
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/fsdp.md
@@ -0,0 +1,138 @@
+
+
+# 완전 분할 데이터 병렬 처리(FSDP) [[fully-sharded-data-parallel]]
+
+[Fully Sharded Data Parallel (FSDP)](https://pytorch.org/blog/introducing-pytorch-fully-sharded-data-parallel-api/)은 모델의 매개변수, 그레이디언트 및 옵티마이저 상태를 사용 가능한 GPU(작업자 또는 *랭크*라고도 함) 수에 따라 분할하는 데이터 병렬 처리 방식입니다. [DistributedDataParallel (DDP)](https://pytorch.org/docs/stable/generated/torch.nn.parallel.DistributedDataParallel.html)와 달리, FSDP는 각 GPU에 모델을 복제하기 때문에 메모리 사용량을 줄입니다. 이는 GPU 메모리 효율성을 향상시키며 적은 수의 GPU로 훨씬 더 큰 모델을 훈련할 수 있게 합니다. FSDP는 분산 환경에서의 훈련을 쉽게 관리할 수 있는 라이브러리인 Accelerate와 통합되어 있으며, 따라서 [`Trainer`] 클래스에서 사용할 수 있습니다.
+
+시작하기 전에 Accelerate가 설치되어 있고 최소 PyTorch 2.1.0 이상의 버전이 설치되어 있는지 확인하세요.
+
+```bash
+pip install accelerate
+```
+
+## FSDP 구성 [[fsdp-configuration]]
+
+시작하려면 [`accelerate config`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-config) 명령을 실행하여 훈련 환경에 대한 구성 파일을 생성하세요. Accelerate는 이 구성 파일을 사용하여 `accelerate config`에서 선택한 훈련 옵션에 따라 자동으로 올바른 훈련 환경을 설정합니다.
+
+```bash
+accelerate config
+```
+
+`accelerate config`를 실행하면 훈련 환경을 구성하기 위한 일련의 옵션들이 나타납니다. 이 섹션에서는 가장 중요한 FSDP 옵션 중 일부를 다룹니다. 다른 사용 가능한 FSDP 옵션에 대해 더 알아보고 싶다면 [fsdp_config](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.fsdp_config) 매개변수를 참조하세요.
+
+### 분할 전략 [[sharding-strategy]]
+
+FSDP는 여러 가지 분할 전략을 제공합니다:
+
+* `FULL_SHARD` - 모델 매개변수, 그레이디언트 및 옵티마이저 상태를 작업자 간에 분할; 이 옵션을 선택하려면 `1`을 선택하세요
+* `SHARD_GRAD_OP` - 그레이디언트 및 옵티마이저 상태를 작업자 간에 분할; 이 옵션을 선택하려면 `2`를 선택하세요
+* `NO_SHARD` - 아무 것도 분할하지 않음 (DDP와 동일); 이 옵션을 선택하려면 `3`을 선택하세요
+* `HYBRID_SHARD` - 각 작업자가 전체 복사본을 가지고 있는 상태에서 모델 매개변수, 그레이디언트 및 옵티마이저 상태를 작업자 내에서 분할; 이 옵션을 선택하려면 `4`를 선택하세요
+* `HYBRID_SHARD_ZERO2` - 각 작업자가 전체 복사본을 가지고 있는 상태에서 그레이디언트 및 옵티마이저 상태를 작업자 내에서 분할; 이 옵션을 선택하려면 `5`를 선택하세요
+
+이것은 `fsdp_sharding_strategy` 플래그로 활성화됩니다.
+
+### CPU 오프로드 [[cpu-offload]]
+
+사용하지 않는 매개변수와 그레이디언트를 CPU로 오프로드하여 더 많은 GPU 메모리를 절약하고 FSDP로도 충분하지 않은 큰 모델을 GPU에 적재할 수 있도록 할 수 있습니다. 이는 `accelerate config`를 실행할 때 `fsdp_offload_params: true`로 설정하여 활성화됩니다.
+
+### 래핑 정책 [[wrapping-policy]]
+
+FSDP는 네트워크의 각 레이어를 래핑하여 적용됩니다. 래핑은 일반적으로 중첩 방식으로 적용되며 각각 순방향으로 지나간 후 전체 가중치를 삭제하여 다음 레이어에서 사용할 메모리를 절약합니다. *자동 래핑* 정책은 이를 구현하는 가장 간단한 방법이며 코드를 변경할 필요가 없습니다. Transformer 레이어를 래핑하려면 `fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP`를 선택하고 래핑할 레이어를 지정하려면 `fsdp_transformer_layer_cls_to_wrap`를 선택하세요 (예: `BertLayer`).
+
+또는 특정 매개변수 수를 초과할 경우 FSDP가 레이어에 적용되는 크기 기반 래핑 정책을 선택할 수 있습니다. 이는 `fsdp_wrap_policy: SIZE_BASED_WRAP` 및 `min_num_param`을 원하는 크기의 임계값으로 설정하여 활성화됩니다.
+
+### 체크포인트 [[checkpointing]]
+
+중간 체크포인트는 `fsdp_state_dict_type: SHARDED_STATE_DICT`로 저장해야 합니다. CPU 오프로드가 활성화된 랭크 0에서 전체 상태 딕셔너리를 저장하는 데 시간이 많이 걸리고, 브로드캐스팅 중 무기한 대기하여 `NCCL Timeout` 오류가 발생할 수 있기 때문입니다. [`~accelerate.Accelerator.load_state`] 메서드를 사용하여 분할된 상태 딕셔너리로 훈련을 재개할 수 있습니다.
+
+```py
+# 경로가 내재된 체크포인트
+accelerator.load_state("ckpt")
+```
+
+그러나 훈련이 끝나면 전체 상태 딕셔너리를 저장해야 합니다. 분할된 상태 딕셔너리는 FSDP와만 호환되기 때문입니다.
+
+```py
+if trainer.is_fsdp_enabled:
+ trainer.accelerator.state.fsdp_plugin.set_state_dict_type("FULL_STATE_DICT")
+
+trainer.save_model(script_args.output_dir)
+```
+
+### TPU [[tpu]]
+
+[PyTorch XLA](https://pytorch.org/xla/release/2.1/index.html)는 TPU에 대한 FSDP 훈련을 지원하며 `accelerate config`로 생성된 FSDP 구성 파일을 수정하여 활성화할 수 있습니다. 위에서 지정한 분할 전략 및 래핑 옵션 외에도 아래에 표시된 매개변수를 파일에 추가할 수 있습니다.
+
+```yaml
+xla: True # PyTorch/XLA를 활성화하려면 True로 설정해야 합니다
+xla_fsdp_settings: # XLA 특정 FSDP 매개변수
+xla_fsdp_grad_ckpt: True # gradient checkpointing을 사용합니다
+```
+
+[`xla_fsdp_settings`](https://github.com/pytorch/xla/blob/2e6e183e0724818f137c8135b34ef273dea33318/torch_xla/distributed/fsdp/xla_fully_sharded_data_parallel.py#L128)는 FSDP에 대한 추가적인 XLA 특정 매개변수를 구성할 수 있게 합니다.
+
+## 훈련 시작 [[launch-training]]
+
+예시 FSDP 구성 파일은 다음과 같을 수 있습니다:
+
+```yaml
+compute_environment: LOCAL_MACHINE
+debug: false
+distributed_type: FSDP
+downcast_bf16: 'no'
+fsdp_config:
+ fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
+ fsdp_backward_prefetch_policy: BACKWARD_PRE
+ fsdp_cpu_ram_efficient_loading: true
+ fsdp_forward_prefetch: false
+ fsdp_offload_params: true
+ fsdp_sharding_strategy: 1
+ fsdp_state_dict_type: SHARDED_STATE_DICT
+ fsdp_sync_module_states: true
+ fsdp_transformer_layer_cls_to_wrap: BertLayer
+ fsdp_use_orig_params: true
+machine_rank: 0
+main_training_function: main
+mixed_precision: bf16
+num_machines: 1
+num_processes: 2
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+훈련을 시작하려면 [`accelerate launch`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-launch) 명령을 실행하세요. 이 때 전에 `accelerate config`로 생성한 구성 파일을 자동으로 사용합니다.
+
+```bash
+accelerate launch my-trainer-script.py
+```
+
+```bash
+accelerate launch --fsdp="full shard" --fsdp_config="path/to/fsdp_config/ my-trainer-script.py
+```
+
+## 다음 단계 [[next-steps]]
+
+FSDP는 매우 큰 모델을 훈련할 때 강력한 도구가 될 수 있으며, 여러 개의 GPU나 TPU를 사용할 수 있습니다. 모델 매개변수, 옵티마이저 및 그레이디언트 상태를 분할하고 비활성 상태일 때, CPU로 오프로드하면 FSDP는 대규모 훈련의 높은 연산 비용을 줄일 수 있습니다. 더 알아보고 싶다면 다음 자료가 도움이 될 수 있습니다:
+
+* [FSDP](https://huggingface.co/docs/accelerate/usage_guides/fsdp)에 대한 더 깊이 있는 Accelerate 가이드를 따라가 보세요.
+* [PyTorch의 완전 분할 데이터 병렬 처리 (FSDP) API를 소개합니다](https://pytorch.org/blog/introducing-pytorch-fully-sharded-data-parallel-api/) 블로그 글을 읽어보세요.
+* [FSDP를 사용하여 클라우드 TPU에서 PyTorch 모델 크기 조절하기](https://pytorch.org/blog/scaling-pytorch-models-on-cloud-tpus-with-fsdp/) 블로그 글을 읽어보세요.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/generation_strategies.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/generation_strategies.md
new file mode 100644
index 0000000000000000000000000000000000000000..05f81c008b30f153932258968ed72c01888e35f2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/generation_strategies.md
@@ -0,0 +1,337 @@
+
+
+# Text generation strategies[[text-generation-strategies]]
+
+텍스트 생성은 개방형 텍스트 작성, 요약, 번역 등 다양한 자연어 처리(NLP) 작업에 필수적입니다. 이는 또한 음성-텍스트 변환, 시각-텍스트 변환과 같이 텍스트를 출력으로 하는 여러 혼합 모달리티 응용 프로그램에서도 중요한 역할을 합니다. 텍스트 생성을 가능하게 하는 몇몇 모델로는 GPT2, XLNet, OpenAI GPT, CTRL, TransformerXL, XLM, Bart, T5, GIT, Whisper 등이 있습니다.
+
+
+[`~generation.GenerationMixin.generate`] 메서드를 활용하여 다음과 같은 다양한 작업들에 대해 텍스트 결과물을 생성하는 몇 가지 예시를 살펴보세요:
+* [텍스트 요약](./tasks/summarization#inference)
+* [이미지 캡셔닝](./model_doc/git#transformers.GitForCausalLM.forward.example)
+* [오디오 전사](./model_doc/whisper#transformers.WhisperForConditionalGeneration.forward.example)
+
+generate 메소드에 입력되는 값들은 모델의 데이터 형태에 따라 달라집니다. 이 값들은 AutoTokenizer나 AutoProcessor와 같은 모델의 전처리 클래스에 의해 반환됩니다. 모델의 전처리 장치가 하나 이상의 입력 유형을 생성하는 경우, 모든 입력을 generate()에 전달해야 합니다. 각 모델의 전처리 장치에 대해서는 해당 모델의 문서에서 자세히 알아볼 수 있습니다.
+
+텍스트를 생성하기 위해 출력 토큰을 선택하는 과정을 디코딩이라고 하며, `generate()` 메소드가 사용할 디코딩 전략을 사용자가 커스터마이징할 수 있습니다. 디코딩 전략을 수정하는 것은 훈련 가능한 매개변수의 값들을 변경하지 않지만, 생성된 출력의 품질에 눈에 띄는 영향을 줄 수 있습니다. 이는 텍스트에서 반복을 줄이고, 더 일관성 있게 만드는 데 도움을 줄 수 있습니다.
+
+
+이 가이드에서는 다음과 같은 내용을 다룹니다:
+* 기본 생성 설정
+* 일반적인 디코딩 전략과 주요 파라미터
+* 🤗 Hub에서 미세 조정된 모델과 함께 사용자 정의 생성 설정을 저장하고 공유하는 방법
+
+## 기본 텍스트 생성 설정[[default-text-generation-configuration]]
+
+모델의 디코딩 전략은 생성 설정에서 정의됩니다. 사전 훈련된 모델을 [`pipeline`] 내에서 추론에 사용할 때, 모델은 내부적으로 기본 생성 설정을 적용하는 `PreTrainedModel.generate()` 메소드를 호출합니다. 사용자가 모델과 함께 사용자 정의 설정을 저장하지 않았을 경우에도 기본 설정이 사용됩니다.
+
+모델을 명시적으로 로드할 때, `model.generation_config`을 통해 제공되는 생성 설정을 검사할 수 있습니다.
+
+```python
+>>> from transformers import AutoModelForCausalLM
+
+>>> model = AutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+>>> model.generation_config
+GenerationConfig {
+ "bos_token_id": 50256,
+ "eos_token_id": 50256,
+}
+```
+
+ `model.generation_config`를 출력하면 기본 설정과 다른 값들만 표시되고, 기본값들은 나열되지 않습니다.
+
+기본 생성 설정은 입력 프롬프트와 출력을 합친 최대 크기를 20 토큰으로 제한하여 리소스 부족을 방지합니다. 기본 디코딩 전략은 탐욕 탐색(greedy search)으로, 다음 토큰으로 가장 높은 확률을 가진 토큰을 선택하는 가장 단순한 디코딩 전략입니다. 많은 작업과 작은 출력 크기에 대해서는 이 방법이 잘 작동하지만, 더 긴 출력을 생성할 때 사용하면 매우 반복적인 결과를 생성하게 될 수 있습니다.
+
+## 텍스트 생성 사용자 정의[[customize-text-generation]]
+
+파라미터와 해당 값을 [`generate`] 메소드에 직접 전달하여 `generation_config`을 재정의할 수 있습니다:
+
+```python
+>>> my_model.generate(**inputs, num_beams=4, do_sample=True) # doctest: +SKIP
+```
+
+기본 디코딩 전략이 대부분의 작업에 잘 작동한다 하더라도, 조정할 수 있는 몇 가지 파라미터가 있습니다. 일반적으로 조정되는 파라미터에는 다음과 같은 것들이 포함됩니다:
+
+- `max_new_tokens`: 생성할 최대 토큰 수입니다. 즉, 프롬프트에 있는 토큰을 제외한 출력 시퀀스의 크기입니다. 출력의 길이를 중단 기준으로 사용하는 대신, 전체 생성물이 일정 시간을 초과할 때 생성을 중단하기로 선택할 수도 있습니다. 더 알아보려면 [`StoppingCriteria`]를 확인하세요.
+- `num_beams`: 1보다 큰 수의 빔을 지정함으로써, 탐욕 탐색(greedy search)에서 빔 탐색(beam search)으로 전환하게 됩니다. 이 전략은 각 시간 단계에서 여러 가설을 평가하고 결국 전체 시퀀스에 대해 가장 높은 확률을 가진 가설을 선택합니다. 이는 초기 토큰의 확률이 낮아 탐욕 탐색에 의해 무시되었을 높은 확률의 시퀀스를 식별할 수 있는 장점을 가집니다.
+- `do_sample`: 이 매개변수를 `True`로 설정하면, 다항 샘플링, 빔 탐색 다항 샘플링, Top-K 샘플링 및 Top-p 샘플링과 같은 디코딩 전략을 활성화합니다. 이러한 전략들은 전체 어휘에 대한 확률 분포에서 다음 토큰을 선택하며, 전략별로 특정 조정이 적용됩니다.
+- `num_return_sequences`: 각 입력에 대해 반환할 시퀀스 후보의 수입니다. 이 옵션은 빔 탐색(beam search)의 변형과 샘플링과 같이 여러 시퀀스 후보를 지원하는 디코딩 전략에만 사용할 수 있습니다. 탐욕 탐색(greedy search)과 대조 탐색(contrastive search) 같은 디코딩 전략은 단일 출력 시퀀스를 반환합니다.
+
+## 모델에 사용자 정의 디코딩 전략 저장[[save-a-custom-decoding-strategy-with-your-model]]
+
+특정 생성 설정을 가진 미세 조정된 모델을 공유하고자 할 때, 다음 단계를 따를 수 있습니다:
+* [`GenerationConfig`] 클래스 인스턴스를 생성합니다.
+* 디코딩 전략 파라미터를 설정합니다.
+* 생성 설정을 [`GenerationConfig.save_pretrained`]를 사용하여 저장하며, `config_file_name` 인자는 비워둡니다.
+* 모델의 저장소에 설정을 업로드하기 위해 `push_to_hub`를 `True`로 설정합니다.
+
+```python
+>>> from transformers import AutoModelForCausalLM, GenerationConfig
+
+>>> model = AutoModelForCausalLM.from_pretrained("my_account/my_model") # doctest: +SKIP
+>>> generation_config = GenerationConfig(
+... max_new_tokens=50, do_sample=True, top_k=50, eos_token_id=model.config.eos_token_id
+... )
+>>> generation_config.save_pretrained("my_account/my_model", push_to_hub=True) # doctest: +SKIP
+```
+
+단일 디렉토리에 여러 생성 설정을 저장할 수 있으며, 이때 [`GenerationConfig.save_pretrained`]의 `config_file_name` 인자를 사용합니다. 나중에 [`GenerationConfig.from_pretrained`]로 이들을 인스턴스화할 수 있습니다. 이는 단일 모델에 대해 여러 생성 설정을 저장하고 싶을 때 유용합니다(예: 샘플링을 이용한 창의적 텍스트 생성을 위한 하나, 빔 탐색을 이용한 요약을 위한 다른 하나 등). 모델에 설정 파일을 추가하기 위해 적절한 Hub 권한을 가지고 있어야 합니다.
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer, GenerationConfig
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("google-t5/t5-small")
+
+>>> translation_generation_config = GenerationConfig(
+... num_beams=4,
+... early_stopping=True,
+... decoder_start_token_id=0,
+... eos_token_id=model.config.eos_token_id,
+... pad_token=model.config.pad_token_id,
+... )
+
+>>> # 팁: Hub에 push하려면 `push_to_hub=True`를 추가
+>>> translation_generation_config.save_pretrained("/tmp", "translation_generation_config.json")
+
+>>> # 명명된 생성 설정 파일을 사용하여 생성을 매개변수화할 수 있습니다.
+>>> generation_config = GenerationConfig.from_pretrained("/tmp", "translation_generation_config.json")
+>>> inputs = tokenizer("translate English to French: Configuration files are easy to use!", return_tensors="pt")
+>>> outputs = model.generate(**inputs, generation_config=generation_config)
+>>> print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['Les fichiers de configuration sont faciles à utiliser!']
+```
+
+## 스트리밍[[streaming]]
+
+`generate()` 메소드는 `streamer` 입력을 통해 스트리밍을 지원합니다. `streamer` 입력은 `put()`과 `end()` 메소드를 가진 클래스의 인스턴스와 호환됩니다. 내부적으로, `put()`은 새 토큰을 추가하는 데 사용되며, `end()`는 텍스트 생성의 끝을 표시하는 데 사용됩니다.
+
+
+
+스트리머 클래스의 API는 아직 개발 중이며, 향후 변경될 수 있습니다.
+
+
+
+실제로 다양한 목적을 위해 자체 스트리밍 클래스를 만들 수 있습니다! 또한, 기본적인 스트리밍 클래스들도 준비되어 있어 바로 사용할 수 있습니다. 예를 들어, [`TextStreamer`] 클래스를 사용하여 `generate()`의 출력을 화면에 한 단어씩 스트리밍할 수 있습니다:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, TextStreamer
+
+>>> tok = AutoTokenizer.from_pretrained("openai-community/gpt2")
+>>> model = AutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+>>> inputs = tok(["An increasing sequence: one,"], return_tensors="pt")
+>>> streamer = TextStreamer(tok)
+
+>>> # 스트리머는 평소와 같은 출력값을 반환할 뿐만 아니라 생성된 텍스트도 표준 출력(stdout)으로 출력합니다.
+>>> _ = model.generate(**inputs, streamer=streamer, max_new_tokens=20)
+An increasing sequence: one, two, three, four, five, six, seven, eight, nine, ten, eleven,
+```
+
+## 디코딩 전략[[decoding-strategies]]
+
+`generate()` 매개변수와 궁극적으로 `generation_config`의 특정 조합을 사용하여 특정 디코딩 전략을 활성화할 수 있습니다. 이 개념이 처음이라면, 흔히 사용되는 디코딩 전략이 어떻게 작동하는지 설명하는 [이 블로그 포스트](https://huggingface.co/blog/how-to-generate)를 읽어보는 것을 추천합니다.
+
+여기서는 디코딩 전략을 제어하는 몇 가지 매개변수를 보여주고, 이를 어떻게 사용할 수 있는지 설명하겠습니다.
+
+### 탐욕 탐색(Greedy Search)[[greedy-search]]
+
+[`generate`]는 기본적으로 탐욕 탐색 디코딩을 사용하므로 이를 활성화하기 위해 별도의 매개변수를 지정할 필요가 없습니다. 이는 `num_beams`가 1로 설정되고 `do_sample=False`로 되어 있다는 의미입니다."
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> prompt = "I look forward to"
+>>> checkpoint = "distilbert/distilgpt2"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+>>> outputs = model.generate(**inputs)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['I look forward to seeing you all again!\n\n\n\n\n\n\n\n\n\n\n']
+```
+
+### 대조 탐색(Contrastive search)[[contrastive-search]]
+
+2022년 논문 [A Contrastive Framework for Neural Text Generation](https://arxiv.org/abs/2202.06417)에서 제안된 대조 탐색 디코딩 전략은 반복되지 않으면서도 일관된 긴 출력을 생성하는 데 있어 우수한 결과를 보였습니다. 대조 탐색이 작동하는 방식을 알아보려면 [이 블로그 포스트](https://huggingface.co/blog/introducing-csearch)를 확인하세요. 대조 탐색의 동작을 가능하게 하고 제어하는 두 가지 주요 매개변수는 `penalty_alpha`와 `top_k`입니다:
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForCausalLM
+
+>>> checkpoint = "openai-community/gpt2-large"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+
+>>> prompt = "Hugging Face Company is"
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> outputs = model.generate(**inputs, penalty_alpha=0.6, top_k=4, max_new_tokens=100)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Hugging Face Company is a family owned and operated business. We pride ourselves on being the best
+in the business and our customer service is second to none.\n\nIf you have any questions about our
+products or services, feel free to contact us at any time. We look forward to hearing from you!']
+```
+
+### 다항 샘플링(Multinomial sampling)[[multinomial-sampling]]
+
+탐욕 탐색(greedy search)이 항상 가장 높은 확률을 가진 토큰을 다음 토큰으로 선택하는 것과 달리, 다항 샘플링(multinomial sampling, 조상 샘플링(ancestral sampling)이라고도 함)은 모델이 제공하는 전체 어휘에 대한 확률 분포를 기반으로 다음 토큰을 무작위로 선택합니다. 0이 아닌 확률을 가진 모든 토큰은 선택될 기회가 있으므로, 반복의 위험을 줄일 수 있습니다.
+
+다항 샘플링을 활성화하려면 `do_sample=True` 및 `num_beams=1`을 설정하세요.
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForCausalLM, set_seed
+>>> set_seed(0) # 재현성을 위해
+
+>>> checkpoint = "openai-community/gpt2-large"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+
+>>> prompt = "Today was an amazing day because"
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> outputs = model.generate(**inputs, do_sample=True, num_beams=1, max_new_tokens=100)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Today was an amazing day because when you go to the World Cup and you don\'t, or when you don\'t get invited,
+that\'s a terrible feeling."']
+```
+
+### 빔 탐색(Beam-search) 디코딩[[beam-search-decoding]]
+
+탐욕 검색(greedy search)과 달리, 빔 탐색(beam search) 디코딩은 각 시간 단계에서 여러 가설을 유지하고 결국 전체 시퀀스에 대해 가장 높은 확률을 가진 가설을 선택합니다. 이는 낮은 확률의 초기 토큰으로 시작하고 그리디 검색에서 무시되었을 가능성이 높은 시퀀스를 식별하는 이점이 있습니다.
+
+이 디코딩 전략을 활성화하려면 `num_beams` (추적할 가설 수라고도 함)를 1보다 크게 지정하세요.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> prompt = "It is astonishing how one can"
+>>> checkpoint = "openai-community/gpt2-medium"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+
+>>> outputs = model.generate(**inputs, num_beams=5, max_new_tokens=50)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['It is astonishing how one can have such a profound impact on the lives of so many people in such a short period of
+time."\n\nHe added: "I am very proud of the work I have been able to do in the last few years.\n\n"I have']
+```
+
+### 빔 탐색 다항 샘플링(Beam-search multinomial sampling)[[beam-search-multinomial-sampling]]
+
+이 디코딩 전략은 이름에서 알 수 있듯이 빔 탐색과 다항 샘플링을 결합한 것입니다. 이 디코딩 전략을 사용하기 위해서는 `num_beams`를 1보다 큰 값으로 설정하고, `do_sample=True`로 설정해야 합니다.
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM, set_seed
+>>> set_seed(0) # 재현성을 위해
+
+>>> prompt = "translate English to German: The house is wonderful."
+>>> checkpoint = "google-t5/t5-small"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+
+>>> outputs = model.generate(**inputs, num_beams=5, do_sample=True)
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'Das Haus ist wunderbar.'
+```
+
+### 다양한 빔 탐색 디코딩(Diverse beam search decoding)[[diverse-beam-search-decoding]]
+
+다양한 빔 탐색(Decoding) 전략은 선택할 수 있는 더 다양한 빔 시퀀스 집합을 생성할 수 있게 해주는 빔 탐색 전략의 확장입니다. 이 방법은 어떻게 작동하는지 알아보려면, [다양한 빔 탐색: 신경 시퀀스 모델에서 다양한 솔루션 디코딩하기](https://arxiv.org/pdf/1610.02424.pdf)를 참조하세요. 이 접근 방식은 세 가지 주요 매개변수를 가지고 있습니다: `num_beams`, `num_beam_groups`, 그리고 `diversity_penalty`. 다양성 패널티는 그룹 간에 출력이 서로 다르게 하기 위한 것이며, 각 그룹 내에서 빔 탐색이 사용됩니다.
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+>>> checkpoint = "google/pegasus-xsum"
+>>> prompt = (
+... "The Permaculture Design Principles are a set of universal design principles "
+... "that can be applied to any location, climate and culture, and they allow us to design "
+... "the most efficient and sustainable human habitation and food production systems. "
+... "Permaculture is a design system that encompasses a wide variety of disciplines, such "
+... "as ecology, landscape design, environmental science and energy conservation, and the "
+... "Permaculture design principles are drawn from these various disciplines. Each individual "
+... "design principle itself embodies a complete conceptual framework based on sound "
+... "scientific principles. When we bring all these separate principles together, we can "
+... "create a design system that both looks at whole systems, the parts that these systems "
+... "consist of, and how those parts interact with each other to create a complex, dynamic, "
+... "living system. Each design principle serves as a tool that allows us to integrate all "
+... "the separate parts of a design, referred to as elements, into a functional, synergistic, "
+... "whole system, where the elements harmoniously interact and work together in the most "
+... "efficient way possible."
+... )
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+
+>>> outputs = model.generate(**inputs, num_beams=5, num_beam_groups=5, max_new_tokens=30, diversity_penalty=1.0)
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'The Design Principles are a set of universal design principles that can be applied to any location, climate and
+culture, and they allow us to design the'
+```
+
+이 가이드에서는 다양한 디코딩 전략을 가능하게 하는 주요 매개변수를 보여줍니다. [`generate`] 메서드에 대한 고급 매개변수가 존재하므로 [`generate`] 메서드의 동작을 더욱 세부적으로 제어할 수 있습니다. 사용 가능한 매개변수의 전체 목록은 [API 문서](./main_classes/text_generation.md)를 참조하세요.
+
+### 추론 디코딩(Speculative Decoding)[[speculative-decoding]]
+
+추론 디코딩(보조 디코딩(assisted decoding)으로도 알려짐)은 동일한 토크나이저를 사용하는 훨씬 작은 보조 모델을 활용하여 몇 가지 후보 토큰을 생성하는 상위 모델의 디코딩 전략을 수정한 것입니다. 주 모델은 단일 전방 통과로 후보 토큰을 검증함으로써 디코딩 과정을 가속화합니다. `do_sample=True`일 경우, [추론 디코딩 논문](https://arxiv.org/pdf/2211.17192.pdf)에 소개된 토큰 검증과 재샘플링 방식이 사용됩니다.
+
+현재, 탐욕 검색(greedy search)과 샘플링만이 지원되는 보조 디코딩(assisted decoding) 기능을 통해, 보조 디코딩은 배치 입력을 지원하지 않습니다. 보조 디코딩에 대해 더 알고 싶다면, [이 블로그 포스트](https://huggingface.co/blog/assisted-generation)를 확인해 주세요.
+
+보조 디코딩을 활성화하려면 모델과 함께 `assistant_model` 인수를 설정하세요.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> prompt = "Alice and Bob"
+>>> checkpoint = "EleutherAI/pythia-1.4b-deduped"
+>>> assistant_checkpoint = "EleutherAI/pythia-160m-deduped"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+>>> assistant_model = AutoModelForCausalLM.from_pretrained(assistant_checkpoint)
+>>> outputs = model.generate(**inputs, assistant_model=assistant_model)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Alice and Bob are sitting in a bar. Alice is drinking a beer and Bob is drinking a']
+```
+
+샘플링 방법과 함께 보조 디코딩을 사용하는 경우 다항 샘플링과 마찬가지로 `temperature` 인수를 사용하여 무작위성을 제어할 수 있습니다. 그러나 보조 디코딩에서는 `temperature`를 낮추면 대기 시간을 개선하는 데 도움이 될 수 있습니다.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, set_seed
+>>> set_seed(42) # 재현성을 위해
+
+>>> prompt = "Alice and Bob"
+>>> checkpoint = "EleutherAI/pythia-1.4b-deduped"
+>>> assistant_checkpoint = "EleutherAI/pythia-160m-deduped"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+>>> assistant_model = AutoModelForCausalLM.from_pretrained(assistant_checkpoint)
+>>> outputs = model.generate(**inputs, assistant_model=assistant_model, do_sample=True, temperature=0.5)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Alice and Bob, who were both in their early twenties, were both in the process of']
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/gguf.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/gguf.md
new file mode 100644
index 0000000000000000000000000000000000000000..03bd7c08bb2691c5214999cbe00d9e3cdacadfe2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/gguf.md
@@ -0,0 +1,100 @@
+
+
+# GGUF와 Transformers의 상호작용 [[gguf-and-interaction-with-transformers]]
+
+GGUF 파일 형식은 [GGML](https://github.com/ggerganov/ggml)과 그에 의존하는 다른 라이브러리, 예를 들어 매우 인기 있는 [llama.cpp](https://github.com/ggerganov/llama.cpp)이나 [whisper.cpp](https://github.com/ggerganov/whisper.cpp)에서 추론을 위한 모델을 저장하는데 사용됩니다.
+
+이 파일 형식은 [Hugging Face Hub](https://huggingface.co/docs/hub/en/gguf)에서 지원되며, 파일 내의 텐서와 메타데이터를 신속하게 검사할 수 있는 기능을 제공합니다.
+
+이 형식은 "단일 파일 형식(single-file-format)"으로 설계되었으며, 하나의 파일에 설정 속성, 토크나이저 어휘, 기타 속성뿐만 아니라 모델에서 로드되는 모든 텐서가 포함됩니다. 이 파일들은 파일의 양자화 유형에 따라 다른 형식으로 제공됩니다. 다양한 양자화 유형에 대한 간략한 설명은 [여기](https://huggingface.co/docs/hub/en/gguf#quantization-types)에서 확인할 수 있습니다.
+
+## Transformers 내 지원 [[support-within-transformers]]
+
+`transformers` 내에서 `gguf` 파일을 로드할 수 있는 기능을 추가하여 GGUF 모델의 추가 학습/미세 조정을 제공한 후 `ggml` 생태계에서 다시 사용할 수 있도록 `gguf` 파일로 변환하는 기능을 제공합니다. 모델을 로드할 때 먼저 FP32로 역양자화한 후, PyTorch에서 사용할 수 있도록 가중치를 로드합니다.
+
+> [!NOTE]
+> 지원은 아직 초기 단계에 있으며, 다양한 양자화 유형과 모델 아키텍처에 대해 이를 강화하기 위한 기여를 환영합니다.
+
+현재 지원되는 모델 아키텍처와 양자화 유형은 다음과 같습니다:
+
+### 지원되는 양자화 유형 [[supported-quantization-types]]
+
+초기에 지원되는 양자화 유형은 Hub에서 공유된 인기 있는 양자화 파일에 따라 결정되었습니다.
+
+- F32
+- F16
+- BF16
+- Q4_0
+- Q4_1
+- Q5_0
+- Q5_1
+- Q8_0
+- Q2_K
+- Q3_K
+- Q4_K
+- Q5_K
+- Q6_K
+- IQ1_S
+- IQ1_M
+- IQ2_XXS
+- IQ2_XS
+- IQ2_S
+- IQ3_XXS
+- IQ3_S
+- IQ4_XS
+- IQ4_NL
+
+> [!NOTE]
+> GGUF 역양자화를 지원하려면 `gguf>=0.10.0` 설치가 필요합니다.
+
+### 지원되는 모델 아키텍처 [[supported-model-architectures]]
+
+현재 지원되는 모델 아키텍처는 Hub에서 매우 인기가 많은 아키텍처들로 제한되어 있습니다:
+
+- LLaMa
+- Mistral
+- Qwen2
+- Qwen2Moe
+- Phi3
+- Bloom
+
+## 사용 예시 [[example-usage]]
+
+`transformers`에서 `gguf` 파일을 로드하려면 `from_pretrained` 메소드에 `gguf_file` 인수를 지정해야 합니다. 동일한 파일에서 토크나이저와 모델을 로드하는 방법은 다음과 같습니다:
+
+```python
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+model_id = "TheBloke/TinyLlama-1.1B-Chat-v1.0-GGUF"
+filename = "tinyllama-1.1b-chat-v1.0.Q6_K.gguf"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id, gguf_file=filename)
+model = AutoModelForCausalLM.from_pretrained(model_id, gguf_file=filename)
+```
+
+이제 PyTorch 생태계에서 모델의 양자화되지 않은 전체 버전에 접근할 수 있으며, 다른 여러 도구들과 결합하여 사용할 수 있습니다.
+
+`gguf` 파일로 다시 변환하려면 llama.cpp의 [`convert-hf-to-gguf.py`](https://github.com/ggerganov/llama.cpp/blob/master/convert-hf-to-gguf.py)를 사용하는 것을 권장합니다.
+
+위의 스크립트를 완료하여 모델을 저장하고 다시 `gguf`로 내보내는 방법은 다음과 같습니다:
+
+```python
+tokenizer.save_pretrained('directory')
+model.save_pretrained('directory')
+
+!python ${path_to_llama_cpp}/convert-hf-to-gguf.py ${directory}
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/hpo_train.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/hpo_train.md
new file mode 100644
index 0000000000000000000000000000000000000000..c0982db5e093b55b750b655ea6e694c0f62826a8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/hpo_train.md
@@ -0,0 +1,124 @@
+
+
+# Trainer API를 사용한 하이퍼파라미터 탐색 [[hyperparameter-search-using-trainer-api]]
+
+🤗 Transformers에서는 🤗 Transformers 모델을 학습시키는데 최적화된 [`Trainer`] 클래스를 제공하기 때문에, 사용자는 직접 훈련 루프를 작성할 필요 없이 더욱 간편하게 학습을 시킬 수 있습니다. 또한, [`Trainer`]는 하이퍼파라미터 탐색을 위한 API를 제공합니다. 이 문서에서 이 API를 활용하는 방법을 예시와 함께 보여드리겠습니다.
+
+## 하이퍼파라미터 탐색 백엔드 [[hyperparameter-search-backend]]
+
+[`Trainer`]는 현재 아래 4가지 하이퍼파라미터 탐색 백엔드를 지원합니다:
+[optuna](https://optuna.org/)와 [sigopt](https://sigopt.com/), [raytune](https://docs.ray.io/en/latest/tune/index.html), [wandb](https://wandb.ai/site/sweeps) 입니다.
+
+하이퍼파라미터 탐색 백엔드로 사용하기 전에 아래의 명령어를 사용하여 라이브러리들을 설치하세요.
+```bash
+pip install optuna/sigopt/wandb/ray[tune]
+```
+
+## 예제에서 하이퍼파라미터 탐색을 활성화하는 방법 [[how-to-enable-hyperparameter-search-in-example]]
+
+하이퍼파라미터 탐색 공간을 정의하세요. 하이퍼파라미터 탐색 백엔드마다 서로 다른 형식이 필요합니다.
+
+sigopt의 경우, 해당 [object_parameter](https://docs.sigopt.com/ai-module-api-references/api_reference/objects/object_parameter) 문서를 참조하여 아래와 같이 작성하세요:
+```py
+>>> def sigopt_hp_space(trial):
+... return [
+... {"bounds": {"min": 1e-6, "max": 1e-4}, "name": "learning_rate", "type": "double"},
+... {
+... "categorical_values": ["16", "32", "64", "128"],
+... "name": "per_device_train_batch_size",
+... "type": "categorical",
+... },
+... ]
+```
+
+optuna의 경우, 해당 [object_parameter](https://optuna.readthedocs.io/en/stable/tutorial/10_key_features/002_configurations.html#sphx-glr-tutorial-10-key-features-002-configurations-py) 문서를 참조하여 아래와 같이 작성하세요:
+
+```py
+>>> def optuna_hp_space(trial):
+... return {
+... "learning_rate": trial.suggest_float("learning_rate", 1e-6, 1e-4, log=True),
+... "per_device_train_batch_size": trial.suggest_categorical("per_device_train_batch_size", [16, 32, 64, 128]),
+... }
+```
+
+raytune의 경우, 해당 [object_parameter](https://docs.ray.io/en/latest/tune/api/search_space.html) 문서를 참조하여 아래와 같이 작성하세요:
+
+```py
+>>> def ray_hp_space(trial):
+... return {
+... "learning_rate": tune.loguniform(1e-6, 1e-4),
+... "per_device_train_batch_size": tune.choice([16, 32, 64, 128]),
+... }
+```
+
+wandb의 경우, 해당 [object_parameter](https://docs.wandb.ai/guides/sweeps/configuration) 문서를 참조하여 아래와 같이 작성하세요:
+
+```py
+>>> def wandb_hp_space(trial):
+... return {
+... "method": "random",
+... "metric": {"name": "objective", "goal": "minimize"},
+... "parameters": {
+... "learning_rate": {"distribution": "uniform", "min": 1e-6, "max": 1e-4},
+... "per_device_train_batch_size": {"values": [16, 32, 64, 128]},
+... },
+... }
+```
+
+`model_init` 함수를 정의하고 이를 [`Trainer`]에 전달하세요. 아래는 그 예시입니다.
+```py
+>>> def model_init(trial):
+... return AutoModelForSequenceClassification.from_pretrained(
+... model_args.model_name_or_path,
+... from_tf=bool(".ckpt" in model_args.model_name_or_path),
+... config=config,
+... cache_dir=model_args.cache_dir,
+... revision=model_args.model_revision,
+... token=True if model_args.use_auth_token else None,
+... )
+```
+
+아래와 같이 `model_init` 함수, 훈련 인수, 훈련 및 테스트 데이터셋, 그리고 평가 함수를 사용하여 [`Trainer`]를 생성하세요:
+
+```py
+>>> trainer = Trainer(
+... model=None,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... processing_class=tokenizer,
+... model_init=model_init,
+... data_collator=data_collator,
+... )
+```
+
+하이퍼파라미터 탐색을 호출하고, 최적의 시험 매개변수를 가져오세요. 백엔드는 `"optuna"`/`"sigopt"`/`"wandb"`/`"ray"` 중에서 선택할 수 있습니다. 방향은 `"minimize"` 또는 `"maximize"` 중 선택하며, 목표를 최소화할 것인지 최대화할 것인지를 결정합니다.
+
+자신만의 compute_objective 함수를 정의할 수 있습니다. 만약 이 함수를 정의하지 않으면, 기본 compute_objective가 호출되고, f1과 같은 평가 지표의 합이 목푯값으로 반환됩니다.
+
+```py
+>>> best_trial = trainer.hyperparameter_search(
+... direction="maximize",
+... backend="optuna",
+... hp_space=optuna_hp_space,
+... n_trials=20,
+... compute_objective=compute_objective,
+... )
+```
+
+## DDP 미세 조정을 위한 하이퍼파라미터 탐색 [[hyperparameter-search-for-ddp-finetune]]
+현재, DDP(Distributed Data Parallelism; 분산 데이터 병렬처리)를 위한 하이퍼파라미터 탐색은 optuna와 sigopt에서 가능합니다. 최상위 프로세스가 하이퍼파라미터 탐색 과정을 시작하고 그 결과를 다른 프로세스에 전달합니다.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/in_translation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/in_translation.md
new file mode 100644
index 0000000000000000000000000000000000000000..61ff1426a4522a90b54a33e3b0c91d8a9a1f4d7c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/in_translation.md
@@ -0,0 +1,5 @@
+
+
+# 열심히 번역 중입니다. 조금 이따 만나요!
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/index.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/index.md
new file mode 100644
index 0000000000000000000000000000000000000000..0726085c5b3ae781f77881a9cbb176db5841bfdc
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/index.md
@@ -0,0 +1,362 @@
+
+
+# 🤗 Transformers
+
+[PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/), [JAX](https://jax.readthedocs.io/en/latest/)를 위한 최첨단 머신러닝
+
+🤗 Transformers는 사전학습된 최첨단 모델들을 쉽게 다운로드하고 훈련시킬 수 있는 API와 도구를 제공합니다. 사전학습된 모델을 쓰면 컴퓨팅 비용과 탄소 배출량이 줄고, 모델을 처음부터 훈련시키는 데 필요한 시간과 리소스를 절약할 수 있습니다. 저희 모델들은 다양한 분야의 태스크를 지원합니다.
+
+📝 **자연어 처리**: 텍스트 분류, 개체명 인식, 질의응답, 언어 모델링, 요약, 번역, 객관식 질의응답, 텍스트 생성
+
+
+## 콘텐츠[[contents]]
+
+저희 기술문서는 크게 5개 섹션으로 나눌 수 있습니다:
+
+- **시작하기**에서 라이브러리를 간단히 훑어보고, 본격적으로 뛰어들 수 있게 설치 방법을 안내합니다.
+- **튜토리얼**에서 라이브러리에 익숙해질 수 있도록 자세하고도 쉽게 기본적인 부분을 안내합니다.
+- **How-to 가이드**에서 언어 모델링을 위해 사전학습된 모델을 파인 튜닝하는 방법이나, 직접 모델을 작성하고 공유하는 방법과 같이 특정 목표를 달성하는 방법을 안내합니다.
+- **개념 가이드**에서 🤗 Transformers의 설계 철학과 함께 모델이나 태스크 뒤에 숨겨진 개념들과 아이디어를 탐구하고 설명을 덧붙입니다.
+- **API**에서 모든 클래스와 함수를 설명합니다.
+
+ - **메인 클래스**에서 configuration, model, tokenizer, pipeline과 같이 제일 중요한 클래스들을 자세히 설명합니다.
+ - **모델**에서 라이브러리 속 구현된 각 모델과 연관된 클래스와 함수를 자세히 설명합니다.
+ - **내부 유틸리티**에서 내부적으로 사용되는 유틸리티 클래스와 함수를 자세히 설명합니다.
+
+### 지원 모델[[supported-models]]
+
+
+
+1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
+1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
+1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
+1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
+1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
+1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
+1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
+1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BLOOM](model_doc/bloom)** (from BigScience workshop) released by the [BigScience Workshop](https://bigscience.huggingface.co/).
+1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499) by Adrian de Wynter and Daniel J. Perry.
+1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
+1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
+1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
+1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
+1. **[CLIPSeg](model_doc/clipseg)** (from University of Göttingen) released with the paper [Image Segmentation Using Text and Image Prompts](https://arxiv.org/abs/2112.10003) by Timo Lüddecke and Alexander Ecker.
+1. **[CodeGen](model_doc/codegen)** (from Salesforce) released with the paper [A Conversational Paradigm for Program Synthesis](https://arxiv.org/abs/2203.13474) by Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Savarese, Caiming Xiong.
+1. **[Conditional DETR](model_doc/conditional_detr)** (from Microsoft Research Asia) released with the paper [Conditional DETR for Fast Training Convergence](https://arxiv.org/abs/2108.06152) by Depu Meng, Xiaokang Chen, Zejia Fan, Gang Zeng, Houqiang Li, Yuhui Yuan, Lei Sun, Jingdong Wang.
+1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
+1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
+1. **[CvT](model_doc/cvt)** (from Microsoft) released with the paper [CvT: Introducing Convolutions to Vision Transformers](https://arxiv.org/abs/2103.15808) by Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang.
+1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
+1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+1. **[Deformable DETR](model_doc/deformable_detr)** (from SenseTime Research) released with the paper [Deformable DETR: Deformable Transformers for End-to-End Object Detection](https://arxiv.org/abs/2010.04159) by Xizhou Zhu, Weijie Su, Lewei Lu, Bin Li, Xiaogang Wang, Jifeng Dai.
+1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
+1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
+1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
+1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) and a German version of DistilBERT.
+1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
+1. **[Donut](model_doc/donut)** (from NAVER), released together with the paper [OCR-free Document Understanding Transformer](https://arxiv.org/abs/2111.15664) by Geewook Kim, Teakgyu Hong, Moonbin Yim, Jeongyeon Nam, Jinyoung Park, Jinyeong Yim, Wonseok Hwang, Sangdoo Yun, Dongyoon Han, Seunghyun Park.
+1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
+1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+1. **[EfficientNet](model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://arxiv.org/abs/1905.11946) by Mingxing Tan and Quoc V. Le.
+1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
+1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[ERNIE](model_doc/ernie)** (from Baidu) released with the paper [ERNIE: Enhanced Representation through Knowledge Integration](https://arxiv.org/abs/1904.09223) by Yu Sun, Shuohuan Wang, Yukun Li, Shikun Feng, Xuyi Chen, Han Zhang, Xin Tian, Danxiang Zhu, Hao Tian, Hua Wu.
+1. **[ESM](model_doc/esm)** (from Meta AI) are transformer protein language models. **ESM-1b** was released with the paper [Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118) by Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott, C. Lawrence Zitnick, Jerry Ma, and Rob Fergus. **ESM-1v** was released with the paper [Language models enable zero-shot prediction of the effects of mutations on protein function](https://doi.org/10.1101/2021.07.09.450648) by Joshua Meier, Roshan Rao, Robert Verkuil, Jason Liu, Tom Sercu and Alexander Rives. **ESM-2 and ESMFold** were released with the paper [Language models of protein sequences at the scale of evolution enable accurate structure prediction](https://doi.org/10.1101/2022.07.20.500902) by Zeming Lin, Halil Akin, Roshan Rao, Brian Hie, Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido, Alexander Rives.
+1. **[FLAN-T5](model_doc/flan-t5)** (from Google AI) released in the repository [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-t5-checkpoints) by Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V. Le, and Jason Wei
+1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
+1. **[FLAVA](model_doc/flava)** (from Facebook AI) released with the paper [FLAVA: A Foundational Language And Vision Alignment Model](https://arxiv.org/abs/2112.04482) by Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela.
+1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
+1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
+1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
+1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
+1. **[GPT NeoX](model_doc/gpt_neox)** (from EleutherAI) released with the paper [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://arxiv.org/abs/2204.06745) by Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach
+1. **[GPT NeoX Japanese](model_doc/gpt_neox_japanese)** (from ABEJA) released by Shinya Otani, Takayoshi Makabe, Anuj Arora, and Kyo Hattori.
+1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
+1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
+1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released in the repository [tanreinama/GPTSAN](https://github.com/tanreinama/GPTSAN/blob/main/report/model.md) by Toshiyuki Sakamoto(tanreinama).
+1. **[GroupViT](model_doc/groupvit)** (from UCSD, NVIDIA) released with the paper [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://arxiv.org/abs/2202.11094) by Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang.
+1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
+1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
+1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
+1. **[Jukebox](model_doc/jukebox)** (from OpenAI) released with the paper [Jukebox: A Generative Model for Music](https://arxiv.org/pdf/2005.00341.pdf) by Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford, Ilya Sutskever.
+1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
+1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
+1. **[LayoutLMv3](model_doc/layoutlmv3)** (from Microsoft Research Asia) released with the paper [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://arxiv.org/abs/2204.08387) by Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
+1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
+1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LeViT](model_doc/levit)** (from Meta AI) released with the paper [LeViT: A Vision Transformer in ConvNet's Clothing for Faster Inference](https://arxiv.org/abs/2104.01136) by Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze.
+1. **[LiLT](model_doc/lilt)** (from South China University of Technology) released with the paper [LiLT: A Simple yet Effective Language-Independent Layout Transformer for Structured Document Understanding](https://arxiv.org/abs/2202.13669) by Jiapeng Wang, Lianwen Jin, Kai Ding.
+1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LongT5](model_doc/longt5)** (from Google AI) released with the paper [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://arxiv.org/abs/2112.07916) by Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung, Yinfei Yang.
+1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
+1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490) by Hao Tan and Mohit Bansal.
+1. **[M-CTC-T](model_doc/mctct)** (from Facebook) released with the paper [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://arxiv.org/abs/2111.00161) by Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert.
+1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
+1. **[MarkupLM](model_doc/markuplm)** (from Microsoft Research Asia) released with the paper [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document Understanding](https://arxiv.org/abs/2110.08518) by Junlong Li, Yiheng Xu, Lei Cui, Furu Wei.
+1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
+1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
+1. **[mBART](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+1. **[mBART-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
+1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
+1. **[MobileBERT](model_doc/mobilebert)** (from CMU/Google Brain) released with the paper [MobileBERT: a Compact Task-Agnostic BERT for Resource-Limited Devices](https://arxiv.org/abs/2004.02984) by Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny Zhou.
+1. **[MobileViT](model_doc/mobilevit)** (from Apple) released with the paper [MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer](https://arxiv.org/abs/2110.02178) by Sachin Mehta and Mohammad Rastegari.
+1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
+1. **[MVP](model_doc/mvp)** (from RUC AI Box) released with the paper [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://arxiv.org/abs/2206.12131) by Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen.
+1. **[Nezha](model_doc/nezha)** (from Huawei Noah’s Ark Lab) released with the paper [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://arxiv.org/abs/1909.00204) by Junqiu Wei, Xiaozhe Ren, Xiaoguang Li, Wenyong Huang, Yi Liao, Yasheng Wang, Jiashu Lin, Xin Jiang, Xiao Chen and Qun Liu.
+1. **[NLLB](model_doc/nllb)** (from Meta) released with the paper [No Language Left Behind: Scaling Human-Centered Machine Translation](https://arxiv.org/abs/2207.04672) by the NLLB team.
+1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
+1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
+1. **[OPT](master/model_doc/opt)** (from Meta AI) released with the paper [OPT: Open Pre-trained Transformer Language Models](https://arxiv.org/abs/2205.01068) by Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al.
+1. **[OWL-ViT](model_doc/owlvit)** (from Google AI) released with the paper [Simple Open-Vocabulary Object Detection with Vision Transformers](https://arxiv.org/abs/2205.06230) by Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby.
+1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
+1. **[PEGASUS-X](model_doc/pegasus_x)** (from Google) released with the paper [Investigating Efficiently Extending Transformers for Long Input Summarization](https://arxiv.org/abs/2208.04347) by Jason Phang, Yao Zhao, and Peter J. Liu.
+1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
+1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
+1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
+1. **[RAG](model_doc/rag)** (from Facebook) released with the paper [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://arxiv.org/abs/2005.11401) by Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela.
+1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
+1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://arxiv.org/abs/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
+1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
+1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
+1. **[RoCBert](model_doc/roc_bert)** (from WeChatAI) released with the paper [RoCBert: Robust Chinese Bert with Multimodal Contrastive Pretraining](https://aclanthology.org/2022.acl-long.65.pdf) by HuiSu, WeiweiShi, XiaoyuShen, XiaoZhou, TuoJi, JiaruiFang, JieZhou.
+1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
+1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
+1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
+1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
+1. **[SqueezeBERT](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
+1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+1. **[Swin Transformer V2](model_doc/swinv2)** (from Microsoft) released with the paper [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883) by Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo.
+1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[Table Transformer](model_doc/table-transformer)** (from Microsoft Research) released with the paper [PubTables-1M: Towards Comprehensive Table Extraction From Unstructured Documents](https://arxiv.org/abs/2110.00061) by Brandon Smock, Rohith Pesala, Robin Abraham.
+1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
+1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
+1. **[Time Series Transformer](model_doc/time_series_transformer)** (from HuggingFace).
+1. **[Trajectory Transformer](model_doc/trajectory_transformers)** (from the University of California at Berkeley) released with the paper [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://arxiv.org/abs/2106.02039) by Michael Janner, Qiyang Li, Sergey Levine
+1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
+1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
+1. **[UL2](model_doc/ul2)** (from Google Research) released with the paper [Unifying Language Learning Paradigms](https://arxiv.org/abs/2205.05131v1) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler
+1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
+1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
+1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://arxiv.org/abs/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+1. **[VideoMAE](model_doc/videomae)** (from Multimedia Computing Group, Nanjing University) released with the paper [VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training](https://arxiv.org/abs/2203.12602) by Zhan Tong, Yibing Song, Jue Wang, Limin Wang.
+1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
+1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
+1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
+1. **[ViTMSN](model_doc/vit_msn)** (from Meta AI) released with the paper [Masked Siamese Networks for Label-Efficient Learning](https://arxiv.org/abs/2204.07141) by Mahmoud Assran, Mathilde Caron, Ishan Misra, Piotr Bojanowski, Florian Bordes, Pascal Vincent, Armand Joulin, Michael Rabbat, Nicolas Ballas.
+1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
+1. **[Wav2Vec2-Conformer](model_doc/wav2vec2-conformer)** (from Facebook AI) released with the paper [FAIRSEQ S2T: Fast Speech-to-Text Modeling with FAIRSEQ](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Sravya Popuri, Dmytro Okhonko, Juan Pino.
+1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
+1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
+1. **[Whisper](model_doc/whisper)** (from OpenAI) released with the paper [Robust Speech Recognition via Large-Scale Weak Supervision](https://cdn.openai.com/papers/whisper.pdf) by Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever.
+1. **[X-CLIP](model_doc/xclip)** (from Microsoft Research) released with the paper [Expanding Language-Image Pretrained Models for General Video Recognition](https://arxiv.org/abs/2208.02816) by Bolin Ni, Houwen Peng, Minghao Chen, Songyang Zhang, Gaofeng Meng, Jianlong Fu, Shiming Xiang, Haibin Ling.
+1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
+1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291) by Guillaume Lample and Alexis Conneau.
+1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
+1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
+1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
+1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
+1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
+1. **[YOLOS](model_doc/yolos)** (from Huazhong University of Science & Technology) released with the paper [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://arxiv.org/abs/2106.00666) by Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu.
+1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
+
+
+### 지원 프레임워크[[supported-framework]]
+
+아래 표는 라이브러리 속 각 모델의 지원 현황을 나타냅니다. 토큰화를 파이썬 (별칭 "slow") 또는 🤗 Tokenizers (별칭 "fast") 라이브러리로 하는지; (Flax를 통한) Jax, PyTorch, TensorFlow 중 어떤 프레임워크를 지원하는지 표시되어 있습니다.
+
+
+
+| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:---------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBird-Pegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BLOOM | ❌ | ✅ | ✅ | ❌ | ❌ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| CANINE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CLIPSeg | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CodeGen | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Conditional DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNeXT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| CvT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Deformable DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DonutSwin | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ERNIE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ESM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FLAVA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
+| GPT NeoX Japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| GroupViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Jukebox | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LayoutLMv3 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LeViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LiLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LongT5 | ❌ | ❌ | ✅ | ❌ | ✅ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M-CTC-T | ❌ | ❌ | ✅ | ❌ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MarkupLM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Megatron-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MobileViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MVP | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Nezha | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Nyströmformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| OPT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| OWL-ViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| PEGASUS-X | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| REALM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoCBert | ✅ | ❌ | ✅ | ❌ | ❌ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| SegFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Swin Transformer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Swin Transformer V2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Table Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Time Series Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VideoMAE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| VisualBERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| ViTMSN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Whisper | ✅ | ❌ | ✅ | ✅ | ❌ |
+| X-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/installation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/installation.md
new file mode 100644
index 0000000000000000000000000000000000000000..a744db40d291236a10b6b93c06d99c0b31a0a33d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/installation.md
@@ -0,0 +1,245 @@
+
+
+# 설치방법[[installation]]
+
+🤗 Transformers를 사용 중인 딥러닝 라이브러리에 맞춰 설치하고, 캐시를 구성하거나 선택적으로 오프라인에서도 실행할 수 있도록 🤗 Transformers를 설정하는 방법을 배우겠습니다.
+
+🤗 Transformers는 Python 3.6+, PyTorch 1.1.0+, TensorFlow 2.0+ 및 Flax에서 테스트되었습니다. 딥러닝 라이브러리를 설치하려면 아래 링크된 저마다의 공식 사이트를 참고해주세요.
+
+* [PyTorch](https://pytorch.org/get-started/locally/) 설치하기
+* [TensorFlow 2.0](https://www.tensorflow.org/install/pip) 설치하기
+* [Flax](https://flax.readthedocs.io/en/latest/) 설치하기
+
+## pip으로 설치하기[[install-with-pip]]
+
+🤗 Transformers를 [가상 환경](https://docs.python.org/3/library/venv.html)에 설치하는 것을 추천드립니다. Python 가상 환경에 익숙하지 않다면, 이 [가이드](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/)를 참고하세요. 가상 환경을 사용하면 서로 다른 프로젝트들을 보다 쉽게 관리할 수 있고, 의존성 간의 호환성 문제를 방지할 수 있습니다.
+
+먼저 프로젝트 디렉토리에서 가상 환경을 만들어 줍니다.
+
+```bash
+python -m venv .env
+```
+
+가상 환경을 활성화해주세요. Linux나 MacOS의 경우:
+
+```bash
+source .env/bin/activate
+```
+Windows의 경우:
+
+```bash
+.env/Scripts/activate
+```
+
+이제 🤗 Transformers를 설치할 준비가 되었습니다. 다음 명령을 입력해주세요.
+
+```bash
+pip install transformers
+```
+
+CPU만 써도 된다면, 🤗 Transformers와 딥러닝 라이브러리를 단 1줄로 설치할 수 있습니다. 예를 들어 🤗 Transformers와 PyTorch의 경우:
+
+```bash
+pip install transformers[torch]
+```
+
+🤗 Transformers와 TensorFlow 2.0의 경우:
+
+```bash
+pip install transformers[tf-cpu]
+```
+
+🤗 Transformers와 Flax의 경우:
+
+```bash
+pip install transformers[flax]
+```
+
+마지막으로 🤗 Transformers가 제대로 설치되었는지 확인할 차례입니다. 사전훈련된 모델을 다운로드하는 코드입니다.
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('we love you'))"
+```
+
+라벨과 점수가 출력되면 잘 설치된 것입니다.
+
+```bash
+[{'label': 'POSITIVE', 'score': 0.9998704791069031}]
+```
+
+## 소스에서 설치하기[[install-from-source]]
+
+🤗 Transformers를 소스에서 설치하려면 아래 명령을 실행하세요.
+
+```bash
+pip install git+https://github.com/huggingface/transformers
+```
+
+위 명령은 최신이지만 (안정적인) `stable` 버전이 아닌 실험성이 짙은 `main` 버전을 설치합니다. `main` 버전은 개발 현황과 발맞추는데 유용합니다. 예시로 마지막 공식 릴리스 이후 발견된 버그가 패치되었지만, 새 릴리스로 아직 롤아웃되지는 않은 경우를 들 수 있습니다. 바꿔 말하면 `main` 버전이 안정성과는 거리가 있다는 뜻이기도 합니다. 저희는 `main` 버전을 사용하는데 문제가 없도록 노력하고 있으며, 대부분의 문제는 대개 몇 시간이나 하루 안에 해결됩니다. 만약 문제가 발생하면 [이슈](https://github.com/huggingface/transformers/issues)를 열어주시면 더 빨리 해결할 수 있습니다!
+
+전과 마찬가지로 🤗 Transformers가 제대로 설치되었는지 확인할 차례입니다.
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('I love you'))"
+```
+
+## 수정 가능한 설치[[editable-install]]
+
+수정 가능한 설치가 필요한 경우는 다음과 같습니다.
+
+* `main` 버전의 소스 코드를 사용하기 위해
+* 🤗 Transformers에 기여하고 싶어서 코드의 변경 사항을 테스트하기 위해
+
+리포지터리를 복제하고 🤗 Transformers를 설치하려면 다음 명령을 입력해주세요.
+
+```bash
+git clone https://github.com/huggingface/transformers.git
+cd transformers
+pip install -e .
+```
+
+위 명령은 리포지터리를 복제한 위치의 폴더와 Python 라이브러리의 경로를 연결시킵니다. Python이 일반 라이브러리 경로 외에 복제한 폴더 내부를 확인할 것입니다. 예를 들어 Python 패키지가 일반적으로 `~/anaconda3/envs/main/lib/python3.7/site-packages/`에 설치되어 있는데, 명령을 받은 Python이 이제 복제한 폴더인 `~/transformers/`도 검색하게 됩니다.
+
+
+
+라이브러리를 계속 사용하려면 `transformers` 폴더를 꼭 유지해야 합니다.
+
+
+
+복제본은 최신 버전의 🤗 Transformers로 쉽게 업데이트할 수 있습니다.
+
+```bash
+cd ~/transformers/
+git pull
+```
+
+Python 환경을 다시 실행하면 업데이트된 🤗 Transformers의 `main` 버전을 찾아낼 것입니다.
+
+## conda로 설치하기[[install-with-conda]]
+
+`conda-forge` conda 채널에서 설치할 수 있습니다.
+
+```bash
+conda install conda-forge::transformers
+```
+
+## 캐시 구성하기[[cache-setup]]
+
+사전훈련된 모델은 다운로드된 후 로컬 경로 `~/.cache/huggingface/hub`에 캐시됩니다. 셸 환경 변수 `TRANSFORMERS_CACHE`의 기본 디렉터리입니다. Windows의 경우 기본 디렉터리는 `C:\Users\username\.cache\huggingface\hub`입니다. 아래의 셸 환경 변수를 (우선 순위) 순서대로 변경하여 다른 캐시 디렉토리를 지정할 수 있습니다.
+
+1. 셸 환경 변수 (기본): `HF_HUB_CACHE` 또는 `TRANSFORMERS_CACHE`
+2. 셸 환경 변수: `HF_HOME`
+3. 셸 환경 변수: `XDG_CACHE_HOME` + `/huggingface`
+
+
+
+과거 🤗 Transformers에서 쓰였던 셸 환경 변수 `PYTORCH_TRANSFORMERS_CACHE` 또는 `PYTORCH_PRETRAINED_BERT_CACHE`이 설정되있다면, 셸 환경 변수 `TRANSFORMERS_CACHE`을 지정하지 않는 한 우선 사용됩니다.
+
+
+
+## 오프라인 모드[[offline-mode]]
+
+🤗 Transformers를 로컬 파일만 사용하도록 해서 방화벽 또는 오프라인 환경에서 실행할 수 있습니다. 활성화하려면 `HF_HUB_OFFLINE=1` 환경 변수를 설정하세요.
+
+
+
+`HF_DATASETS_OFFLINE=1` 환경 변수를 설정하여 오프라인 훈련 과정에 [🤗 Datasets](https://huggingface.co/docs/datasets/)을 추가할 수 있습니다.
+
+
+
+예를 들어 외부 기기 사이에 방화벽을 둔 일반 네트워크에서 평소처럼 프로그램을 다음과 같이 실행할 수 있습니다.
+
+```bash
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+오프라인 기기에서 동일한 프로그램을 다음과 같이 실행할 수 있습니다.
+
+```bash
+HF_DATASETS_OFFLINE=1 HF_HUB_OFFLINE=1 \
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+이제 스크립트는 로컬 파일에 한해서만 검색할 것이므로, 스크립트가 중단되거나 시간이 초과될 때까지 멈춰있지 않고 잘 실행될 것입니다.
+
+### 오프라인용 모델 및 토크나이저 만들어두기[[fetch-models-and-tokenizers-to-use-offline]]
+
+Another option for using 🤗 Transformers offline is to download the files ahead of time, and then point to their local path when you need to use them offline. There are three ways to do this:
+🤗 Transformers를 오프라인으로 사용하는 또 다른 방법은 파일을 미리 다운로드한 다음, 오프라인일 때 사용할 로컬 경로를 지정해두는 것입니다. 3가지 중 편한 방법을 고르세요.
+
+* [Model Hub](https://huggingface.co/models)의 UI를 통해 파일을 다운로드하려면 ↓ 아이콘을 클릭하세요.
+
+ 
+
+* [`PreTrainedModel.from_pretrained`]와 [`PreTrainedModel.save_pretrained`] 워크플로를 활용하세요.
+
+ 1. 미리 [`PreTrainedModel.from_pretrained`]로 파일을 다운로드해두세요.
+
+ ```py
+ >>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("bigscience/T0_3B")
+ >>> model = AutoModelForSeq2SeqLM.from_pretrained("bigscience/T0_3B")
+ ```
+
+ 2. [`PreTrainedModel.save_pretrained`]로 지정된 경로에 파일을 저장해두세요.
+
+ ```py
+ >>> tokenizer.save_pretrained("./your/path/bigscience_t0")
+ >>> model.save_pretrained("./your/path/bigscience_t0")
+ ```
+
+ 3. 이제 오프라인일 때 [`PreTrainedModel.from_pretrained`]로 저장해뒀던 파일을 지정된 경로에서 다시 불러오세요.
+
+ ```py
+ >>> tokenizer = AutoTokenizer.from_pretrained("./your/path/bigscience_t0")
+ >>> model = AutoModel.from_pretrained("./your/path/bigscience_t0")
+ ```
+
+* [huggingface_hub](https://github.com/huggingface/huggingface_hub/tree/main/src/huggingface_hub) 라이브러리를 활용해서 파일을 다운로드하세요.
+
+ 1. 가상환경에 `huggingface_hub` 라이브러리를 설치하세요.
+
+ ```bash
+ python -m pip install huggingface_hub
+ ```
+
+ 2. [`hf_hub_download`](https://huggingface.co/docs/hub/adding-a-library#download-files-from-the-hub) 함수로 파일을 특정 위치에 다운로드할 수 있습니다. 예를 들어 아래 명령은 [T0](https://huggingface.co/bigscience/T0_3B) 모델의 `config.json` 파일을 지정된 경로에 다운로드합니다.
+
+ ```py
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> hf_hub_download(repo_id="bigscience/T0_3B", filename="config.json", cache_dir="./your/path/bigscience_t0")
+ ```
+
+파일을 다운로드하고 로컬에 캐시 해놓고 나면, 나중에 불러와 사용할 수 있도록 로컬 경로를 지정해두세요.
+
+```py
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("./your/path/bigscience_t0/config.json")
+```
+
+
+
+Hub에 저장된 파일을 다운로드하는 방법을 더 자세히 알아보려면 [Hub에서 파일 다운로드하기](https://huggingface.co/docs/hub/how-to-downstream) 섹션을 참고해주세요.
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/audio_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/audio_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..811f7c0866bd509e0b22c53111330cdacd8c4320
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/audio_utils.md
@@ -0,0 +1,39 @@
+
+
+# `FeatureExtractors`를 위한 유틸리티 [[utilities-for-featureextractors]]
+
+이 페이지는 오디오 [`FeatureExtractor`]가 *단시간 푸리에 변환(Short Time Fourier Transform)* 또는 *로그 멜 스펙트로그램(log mel spectrogram)*과 같은 일반적인 알고리즘을 사용하여 원시 오디오에서 특수한 특성을 계산하는 데 사용할 수 있는 유틸리티 함수들을 나열합니다.
+
+이 함수들 대부분은 라이브러리 내 오디오 처리 코드를 연구할 때에만 유용합니다.
+
+## 오디오 변환 [[transformers.audio_utils.hertz_to_mel]]
+
+[[autodoc]] audio_utils.hertz_to_mel
+
+[[autodoc]] audio_utils.mel_to_hertz
+
+[[autodoc]] audio_utils.mel_filter_bank
+
+[[autodoc]] audio_utils.optimal_fft_length
+
+[[autodoc]] audio_utils.window_function
+
+[[autodoc]] audio_utils.spectrogram
+
+[[autodoc]] audio_utils.power_to_db
+
+[[autodoc]] audio_utils.amplitude_to_db
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/file_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/file_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..7effad44baa170fba6b4bc8b954f57c2fd208323
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/file_utils.md
@@ -0,0 +1,50 @@
+
+
+# 일반 유틸리티 (General Utilities) [[general-utilities]]
+
+이 페이지는 `utils.py` 파일에 있는 Transformers의 일반 유틸리티 함수들을 나열합니다.
+
+이 함수들 대부분은 라이브러리의 일반적인 코드를 연구할 때만 유용합니다.
+
+
+## Enums 및 namedtuples [[transformers.utils.ExplicitEnum]]
+
+[[autodoc]] utils.ExplicitEnum
+
+[[autodoc]] utils.PaddingStrategy
+
+[[autodoc]] utils.TensorType
+
+## 특수 데코레이터 (Special Decorators) [[transformers.add_start_docstrings]]
+
+[[autodoc]] utils.add_start_docstrings
+
+[[autodoc]] utils.add_start_docstrings_to_model_forward
+
+[[autodoc]] utils.add_end_docstrings
+
+[[autodoc]] utils.add_code_sample_docstrings
+
+[[autodoc]] utils.replace_return_docstrings
+
+## 특수 속성 (Special Properties) [[transformers.utils.cached_property]]
+
+[[autodoc]] utils.cached_property
+
+## 기타 유틸리티 [[transformers.utils._LazyModule]]
+
+[[autodoc]] utils._LazyModule
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/generation_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/generation_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..a66411f71e9ee8ebb8aa293fa540bda77eeb2d2f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/generation_utils.md
@@ -0,0 +1,413 @@
+
+
+# 생성을 위한 유틸리티 [[utilities-for-generation]]
+
+이 페이지는 [`~generation.GenerationMixin.generate`]에서 사용되는 모든 유틸리티 함수들을 나열합니다.
+
+## 출력을 생성하기 (Generate Outputs) [[generate-outputs]]
+
+[`~generation.GenerationMixin.generate`]의 출력은 [`~utils.ModelOutput`]의 하위 클래스의 인스턴스입니다. 이 출력은 [`~generation.GenerationMixin.generate`]에서 반환되는 모든 정보를 포함하는 데이터 구조체이며, 튜플 또는 딕셔너리로도 사용할 수 있습니다.
+
+다음은 예시입니다:
+
+```python
+from transformers import GPT2Tokenizer, GPT2LMHeadModel
+
+tokenizer = GPT2Tokenizer.from_pretrained("openai-community/gpt2")
+model = GPT2LMHeadModel.from_pretrained("openai-community/gpt2")
+
+inputs = tokenizer("Hello, my dog is cute and ", return_tensors="pt")
+generation_output = model.generate(**inputs, return_dict_in_generate=True, output_scores=True)
+```
+
+`generation_output` 객체는 [`~generation.GenerateDecoderOnlyOutput`]입니다. 아래 문서에서 확인할 수 있듯이, 이 클래스는 다음과 같은 속성을 가지고 있습니다:
+
+- `sequences`: 생성된 토큰 시퀀스
+- `scores` (옵션): 각 생성 단계에서 언어 모델링 헤드의 예측 점수
+- `hidden_states` (옵션): 각 생성 단계에서 모델의 은닉 상태
+- `attentions` (옵션): 각 생성 단계에서 모델의 어텐션 가중치
+
+`output_scores=True`를 전달했기 때문에 `scores`는 포함되어 있지만, `output_hidden_states=True` 또는 `output_attentions=True`를 전달하지 않았으므로 `hidden_states`와 `attentions`는 포함되지 않았습니다.
+
+각 속성은 일반적으로 접근할 수 있으며, 모델이 해당 속성을 반환하지 않았다면 `None`이 반환됩니다. 예를 들어, `generation_output.scores`는 언어 모델링 헤드에서 생성된 모든 예측 점수를 포함하고 있으며, `generation_output.attentions`는 `None`입니다.
+
+`generation_output` 객체를 튜플로 사용할 경우, `None` 값이 아닌 속성만 포함됩니다. 예를 들어, `loss`와 `logits`라는 두 요소가 포함된 경우:
+
+```python
+generation_output[:2]
+```
+
+위 코드는 `(generation_output.sequences, generation_output.scores)` 튜플을 반환합니다.
+
+`generation_output` 객체를 딕셔너리로 사용할 경우, `None` 값이 아닌 속성만 포함됩니다. 예를 들어, `sequences`와 `scores`라는 두 개의 키를 가질 수 있습니다.
+
+여기서는 모든 출력 유형을 문서화합니다.
+
+
+### PyTorch [[transformers.generation.GenerateDecoderOnlyOutput]]
+
+[[autodoc]] generation.GenerateDecoderOnlyOutput
+
+[[autodoc]] generation.GenerateEncoderDecoderOutput
+
+[[autodoc]] generation.GenerateBeamDecoderOnlyOutput
+
+[[autodoc]] generation.GenerateBeamEncoderDecoderOutput
+
+### TensorFlow [[transformers.generation.TFGreedySearchEncoderDecoderOutput]]
+
+[[autodoc]] generation.TFGreedySearchEncoderDecoderOutput
+
+[[autodoc]] generation.TFGreedySearchDecoderOnlyOutput
+
+[[autodoc]] generation.TFSampleEncoderDecoderOutput
+
+[[autodoc]] generation.TFSampleDecoderOnlyOutput
+
+[[autodoc]] generation.TFBeamSearchEncoderDecoderOutput
+
+[[autodoc]] generation.TFBeamSearchDecoderOnlyOutput
+
+[[autodoc]] generation.TFBeamSampleEncoderDecoderOutput
+
+[[autodoc]] generation.TFBeamSampleDecoderOnlyOutput
+
+[[autodoc]] generation.TFContrastiveSearchEncoderDecoderOutput
+
+[[autodoc]] generation.TFContrastiveSearchDecoderOnlyOutput
+
+### FLAX [[transformers.generation.FlaxSampleOutput]]
+
+[[autodoc]] generation.FlaxSampleOutput
+
+[[autodoc]] generation.FlaxGreedySearchOutput
+
+[[autodoc]] generation.FlaxBeamSearchOutput
+
+## LogitsProcessor [[logitsprocessor]]
+
+[`LogitsProcessor`]는 생성 중 언어 모델 헤드의 예측 점수를 수정하는 데 사용됩니다.
+
+### PyTorch [[transformers.AlternatingCodebooksLogitsProcessor]]
+
+[[autodoc]] AlternatingCodebooksLogitsProcessor
+ - __call__
+
+[[autodoc]] ClassifierFreeGuidanceLogitsProcessor
+ - __call__
+
+[[autodoc]] EncoderNoRepeatNGramLogitsProcessor
+ - __call__
+
+[[autodoc]] EncoderRepetitionPenaltyLogitsProcessor
+ - __call__
+
+[[autodoc]] EpsilonLogitsWarper
+ - __call__
+
+[[autodoc]] EtaLogitsWarper
+ - __call__
+
+[[autodoc]] ExponentialDecayLengthPenalty
+ - __call__
+
+[[autodoc]] ForcedBOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] ForcedEOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] HammingDiversityLogitsProcessor
+ - __call__
+
+[[autodoc]] InfNanRemoveLogitsProcessor
+ - __call__
+
+[[autodoc]] LogitNormalization
+ - __call__
+
+[[autodoc]] LogitsProcessor
+ - __call__
+
+[[autodoc]] LogitsProcessorList
+ - __call__
+
+[[autodoc]] MinLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] MinNewTokensLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] MinPLogitsWarper
+ - __call__
+
+[[autodoc]] NoBadWordsLogitsProcessor
+ - __call__
+
+[[autodoc]] NoRepeatNGramLogitsProcessor
+ - __call__
+
+[[autodoc]] PrefixConstrainedLogitsProcessor
+ - __call__
+
+[[autodoc]] RepetitionPenaltyLogitsProcessor
+ - __call__
+
+[[autodoc]] SequenceBiasLogitsProcessor
+ - __call__
+
+[[autodoc]] SuppressTokensAtBeginLogitsProcessor
+ - __call__
+
+[[autodoc]] SuppressTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] TemperatureLogitsWarper
+ - __call__
+
+[[autodoc]] TopKLogitsWarper
+ - __call__
+
+[[autodoc]] TopPLogitsWarper
+ - __call__
+
+[[autodoc]] TypicalLogitsWarper
+ - __call__
+
+[[autodoc]] UnbatchedClassifierFreeGuidanceLogitsProcessor
+ - __call__
+
+[[autodoc]] WhisperTimeStampLogitsProcessor
+ - __call__
+
+[[autodoc]] WatermarkLogitsProcessor
+ - __call__
+
+
+### TensorFlow [[transformers.TFForcedBOSTokenLogitsProcessor]]
+
+[[autodoc]] TFForcedBOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] TFForcedEOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] TFForceTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] TFLogitsProcessor
+ - __call__
+
+[[autodoc]] TFLogitsProcessorList
+ - __call__
+
+[[autodoc]] TFLogitsWarper
+ - __call__
+
+[[autodoc]] TFMinLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] TFNoBadWordsLogitsProcessor
+ - __call__
+
+[[autodoc]] TFNoRepeatNGramLogitsProcessor
+ - __call__
+
+[[autodoc]] TFRepetitionPenaltyLogitsProcessor
+ - __call__
+
+[[autodoc]] TFSuppressTokensAtBeginLogitsProcessor
+ - __call__
+
+[[autodoc]] TFSuppressTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] TFTemperatureLogitsWarper
+ - __call__
+
+[[autodoc]] TFTopKLogitsWarper
+ - __call__
+
+[[autodoc]] TFTopPLogitsWarper
+ - __call__
+
+### FLAX [[transformers.FlaxForcedBOSTokenLogitsProcessor]]
+
+[[autodoc]] FlaxForcedBOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxForcedEOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxForceTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxLogitsProcessorList
+ - __call__
+
+[[autodoc]] FlaxLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxMinLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxSuppressTokensAtBeginLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxSuppressTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxTemperatureLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxTopKLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxTopPLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxWhisperTimeStampLogitsProcessor
+ - __call__
+
+## StoppingCriteria [[transformers.StoppingCriteria]]
+
+[`StoppingCriteria`]는 생성이 언제 멈출지를 결정하는 데 사용됩니다 (EOS 토큰 외). 이 기능은 PyTorch 구현에만 제공됩니다.
+
+[[autodoc]] StoppingCriteria
+ - __call__
+
+[[autodoc]] StoppingCriteriaList
+ - __call__
+
+[[autodoc]] MaxLengthCriteria
+ - __call__
+
+[[autodoc]] MaxTimeCriteria
+ - __call__
+
+[[autodoc]] StopStringCriteria
+ - __call__
+
+[[autodoc]] EosTokenCriteria
+ - __call__
+
+## Constraint [[transformers.Constraint]]
+
+[`Constraint`]는 생성 출력에 특정 토큰이나 시퀀스를 강제로 포함시키는 데 사용됩니다. 이 기능은 PyTorch 구현에만 제공됩니다.
+
+[[autodoc]] Constraint
+
+[[autodoc]] PhrasalConstraint
+
+[[autodoc]] DisjunctiveConstraint
+
+[[autodoc]] ConstraintListState
+
+## 빔 검색 (BeamSearch) [[transformers.BeamScorer]]
+
+[[autodoc]] BeamScorer
+ - process
+ - finalize
+
+[[autodoc]] BeamSearchScorer
+ - process
+ - finalize
+
+[[autodoc]] ConstrainedBeamSearchScorer
+ - process
+ - finalize
+
+## 스트리머 (Streamers) [[transformers.TextStreamer]]
+
+[[autodoc]] TextStreamer
+
+[[autodoc]] TextIteratorStreamer
+
+## 캐시 (Caches) [[transformers.Cache]]
+
+[[autodoc]] Cache
+ - update
+
+[[autodoc]] CacheConfig
+ - update
+
+[[autodoc]] QuantizedCacheConfig
+ - validate
+
+[[autodoc]] DynamicCache
+ - update
+ - get_seq_length
+ - reorder_cache
+ - to_legacy_cache
+ - from_legacy_cache
+
+[[autodoc]] QuantizedCache
+ - update
+ - get_seq_length
+
+[[autodoc]] QuantoQuantizedCache
+
+[[autodoc]] HQQQuantizedCache
+
+[[autodoc]] SinkCache
+ - update
+ - get_seq_length
+ - reorder_cache
+
+[[autodoc]] OffloadedCache
+ - update
+ - prefetch_layer
+ - evict_previous_layer
+
+[[autodoc]] StaticCache
+ - update
+ - get_seq_length
+ - reset
+
+[[autodoc]] OffloadedStaticCache
+ - update
+ - get_seq_length
+ - reset
+
+[[autodoc]] HybridCache
+ - update
+ - get_seq_length
+ - reset
+
+[[autodoc]] SlidingWindowCache
+ - update
+ - reset
+
+[[autodoc]] EncoderDecoderCache
+ - get_seq_length
+ - to_legacy_cache
+ - from_legacy_cache
+ - reset
+ - reorder_cache
+
+[[autodoc]] MambaCache
+ - update_conv_state
+ - update_ssm_state
+ - reset
+
+## 워터마크 유틸리티 (Watermark Utils) [[transformers.WatermarkDetector]]
+
+[[autodoc]] WatermarkDetector
+ - __call__
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/image_processing_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/image_processing_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..cd32935132af8798cffa646b1c4e987834a617ee
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/image_processing_utils.md
@@ -0,0 +1,47 @@
+
+
+# 이미지 프로세서를 위한 유틸리티 [[utilities-for-image-processors]]
+
+이 페이지는 이미지 프로세서에서 사용되는 유틸리티 함수들을 나열하며, 주로 이미지를 처리하기 위한 함수 기반의 변환 작업들을 다룹니다.
+
+이 함수들 대부분은 라이브러리의 이미지 프로세서 코드를 연구할 때만 유용합니다.
+
+## 이미지 변환 [[transformers.image_transforms.center_crop]]
+
+[[autodoc]] image_transforms.center_crop
+
+[[autodoc]] image_transforms.center_to_corners_format
+
+[[autodoc]] image_transforms.corners_to_center_format
+
+[[autodoc]] image_transforms.id_to_rgb
+
+[[autodoc]] image_transforms.normalize
+
+[[autodoc]] image_transforms.pad
+
+[[autodoc]] image_transforms.rgb_to_id
+
+[[autodoc]] image_transforms.rescale
+
+[[autodoc]] image_transforms.resize
+
+[[autodoc]] image_transforms.to_pil_image
+
+## ImageProcessingMixin [[transformers.ImageProcessingMixin]]
+
+[[autodoc]] image_processing_utils.ImageProcessingMixin
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/modeling_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/modeling_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..76cc09db292acdcaf3801713f28f19926ac6e314
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/modeling_utils.md
@@ -0,0 +1,83 @@
+
+
+# 사용자 정의 레이어 및 유틸리티 [[custom-layers-and-utilities]]
+
+이 페이지는 라이브러리에서 사용되는 사용자 정의 레이어와 모델링을 위한 유틸리티 함수들을 나열합니다.
+
+이 함수들 대부분은 라이브러리 내의 모델 코드를 연구할 때만 유용합니다.
+
+
+## PyTorch 사용자 정의 모듈 [[transformers.Conv1D]]
+
+[[autodoc]] pytorch_utils.Conv1D
+
+[[autodoc]] modeling_utils.PoolerStartLogits
+ - forward
+
+[[autodoc]] modeling_utils.PoolerEndLogits
+ - forward
+
+[[autodoc]] modeling_utils.PoolerAnswerClass
+ - forward
+
+[[autodoc]] modeling_utils.SquadHeadOutput
+
+[[autodoc]] modeling_utils.SQuADHead
+ - forward
+
+[[autodoc]] modeling_utils.SequenceSummary
+ - forward
+
+## PyTorch 헬퍼(helper) 함수 [[transformers.apply_chunking_to_forward]]
+
+[[autodoc]] pytorch_utils.apply_chunking_to_forward
+
+[[autodoc]] pytorch_utils.find_pruneable_heads_and_indices
+
+[[autodoc]] pytorch_utils.prune_layer
+
+[[autodoc]] pytorch_utils.prune_conv1d_layer
+
+[[autodoc]] pytorch_utils.prune_linear_layer
+
+## TensorFlow 사용자 정의 레이어 [[transformers.modeling_tf_utils.TFConv1D]]
+
+[[autodoc]] modeling_tf_utils.TFConv1D
+
+[[autodoc]] modeling_tf_utils.TFSequenceSummary
+
+## TensorFlow 손실 함수 [[transformers.modeling_tf_utils.TFCausalLanguageModelingLoss]]
+
+[[autodoc]] modeling_tf_utils.TFCausalLanguageModelingLoss
+
+[[autodoc]] modeling_tf_utils.TFMaskedLanguageModelingLoss
+
+[[autodoc]] modeling_tf_utils.TFMultipleChoiceLoss
+
+[[autodoc]] modeling_tf_utils.TFQuestionAnsweringLoss
+
+[[autodoc]] modeling_tf_utils.TFSequenceClassificationLoss
+
+[[autodoc]] modeling_tf_utils.TFTokenClassificationLoss
+
+## TensorFlow 도우미 함수 [[transformers.modeling_tf_utils.get_initializer]]
+
+[[autodoc]] modeling_tf_utils.get_initializer
+
+[[autodoc]] modeling_tf_utils.keras_serializable
+
+[[autodoc]] modeling_tf_utils.shape_list
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/pipelines_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/pipelines_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..e0e64913145541cc4381df0562861c2b364f1cf2
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/pipelines_utils.md
@@ -0,0 +1,43 @@
+
+
+# 파이프라인을 위한 유틸리티 [[utilities-for-pipelines]]
+
+이 페이지는 라이브러리에서 파이프라인을 위해 제공하는 모든 유틸리티 함수들을 나열합니다.
+
+이 함수들 대부분은 라이브러리 내 모델의 코드를 연구할 때만 유용합니다.
+
+## 인자 처리 [[transformers.pipelines.ArgumentHandler]]
+
+[[autodoc]] pipelines.ArgumentHandler
+
+[[autodoc]] pipelines.ZeroShotClassificationArgumentHandler
+
+[[autodoc]] pipelines.QuestionAnsweringArgumentHandler
+
+## 데이터 형식 [[transformers.PipelineDataFormat]]
+
+[[autodoc]] pipelines.PipelineDataFormat
+
+[[autodoc]] pipelines.CsvPipelineDataFormat
+
+[[autodoc]] pipelines.JsonPipelineDataFormat
+
+[[autodoc]] pipelines.PipedPipelineDataFormat
+
+## 유틸리티 [[transformers.pipelines.PipelineException]]
+
+[[autodoc]] pipelines.PipelineException
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/time_series_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/time_series_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..5729924575b87332223aa5db6c56b6735777b4db
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/time_series_utils.md
@@ -0,0 +1,29 @@
+
+
+# 시계열 유틸리티 [[time-series-utilities]]
+
+이 페이지는 시계열 기반 모델에서 사용할 수 있는 유틸리티 함수와 클래스들을 나열합니다.
+
+이 함수들 대부분은 시계열 모델의 코드를 연구하거나 분포 출력 클래스의 컬렉션에 추가하려는 경우에만 유용합니다.
+
+## 분포 출력 (Distributional Output) [[transformers.time_series_utils.NormalOutput]]
+
+[[autodoc]] time_series_utils.NormalOutput
+
+[[autodoc]] time_series_utils.StudentTOutput
+
+[[autodoc]] time_series_utils.NegativeBinomialOutput
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/tokenization_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/tokenization_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..b5b69910479a2fb42aeaf4d8bd366967ea9f53e7
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/tokenization_utils.md
@@ -0,0 +1,39 @@
+
+
+# 토크나이저를 위한 유틸리티 [[utilities-for-tokenizers]]
+
+이 페이지는 토크나이저에서 사용되는 모든 유틸리티 함수들을 나열하며, 주로 [`PreTrainedTokenizer`]와 [`PreTrainedTokenizerFast`] 사이의 공통 메소드를 구현하는 [`~tokenization_utils_base.PreTrainedTokenizerBase`] 클래스와 [`~tokenization_utils_base.SpecialTokensMixin`]을 다룹니다.
+
+이 함수들 대부분은 라이브러리의 토크나이저 코드를 연구할 때만 유용합니다.
+
+## PreTrainedTokenizerBase [[transformers.PreTrainedTokenizerBase]]
+
+[[autodoc]] tokenization_utils_base.PreTrainedTokenizerBase
+ - __call__
+ - all
+
+## SpecialTokensMixin [[transformers.SpecialTokensMixin]]
+
+[[autodoc]] tokenization_utils_base.SpecialTokensMixin
+
+## Enums 및 namedtuples [[transformers.tokenization_utils_base.TruncationStrategy]]
+
+[[autodoc]] tokenization_utils_base.TruncationStrategy
+
+[[autodoc]] tokenization_utils_base.CharSpan
+
+[[autodoc]] tokenization_utils_base.TokenSpan
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/trainer_utils.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/trainer_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..15fb457331811c6b8cfce23a53766057e816a058
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/internal/trainer_utils.md
@@ -0,0 +1,49 @@
+
+
+# Trainer를 위한 유틸리티 (Utilities for Trainer) [[utilities-for-trainer]]
+
+이 페이지는 [`Trainer`]에서 사용되는 모든 유틸리티 함수들을 나열합니다.
+
+이 함수들 대부분은 라이브러리에 있는 Trainer 코드를 자세히 알아보고 싶을 때만 유용합니다.
+
+## 유틸리티 (Utilities) [[transformers.EvalPrediction]]
+
+[[autodoc]] EvalPrediction
+
+[[autodoc]] IntervalStrategy
+
+[[autodoc]] enable_full_determinism
+
+[[autodoc]] set_seed
+
+[[autodoc]] torch_distributed_zero_first
+
+## 콜백 내부 (Callbacks internals) [[transformers.trainer_callback.CallbackHandler]]
+
+[[autodoc]] trainer_callback.CallbackHandler
+
+## 분산 평가 (Distributed Evaluation) [[transformers.trainer_pt_utils.DistributedTensorGatherer]]
+
+[[autodoc]] trainer_pt_utils.DistributedTensorGatherer
+
+## Trainer 인자 파서 (Trainer Argument Parser) [[transformers.HfArgumentParser]]
+
+[[autodoc]] HfArgumentParser
+
+## 디버그 유틸리티 (Debug Utilities) [[transformers.debug_utils.DebugUnderflowOverflow]]
+
+[[autodoc]] debug_utils.DebugUnderflowOverflow
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/llm_optims.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/llm_optims.md
new file mode 100644
index 0000000000000000000000000000000000000000..99eabc19ce860aa78531e6bf4f0e8c1ca6f43f6e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/llm_optims.md
@@ -0,0 +1,410 @@
+
+
+# LLM 추론 최적화 [[llm-inference-optimization]]
+
+대규모 언어 모델(LLM)은 채팅 및 코드 완성 모델과 같은 텍스트 생성 응용 프로그램을 한 단계 끌어올리며, 높은 수준의 이해력과 유창함을 보여주는 텍스트를 생성합니다. 그러나 LLM을 강력하게 만드는 요소인 그들의 크기는 동시에 추론 과정에서 도전 과제가 되기도 합니다.
+
+기본적인 추론은 느립니다, 왜냐하면 LLM이 다음 토큰을 생성하기 위해 반복적으로 호출되어야 하기 때문입니다. 생성이 진행됨에 따라 입력 시퀀스가 길어져 처리 시간이 점점 길어집니다. 또한, LLM은 수십억 개의 매개변수를 가지고 있어 모든 가중치를 메모리에 저장하고 처리하는 데 어려움이 있습니다.
+
+이 가이드는 LLM 추론을 가속하기 위해 Transformers에서 사용할 수 있는 최적화 기술을 사용하는 방법을 보여줍니다.
+
+> [!TIP]
+> Hugging Face는 LLM을 추론에 최적화하여 배포하고 서비스하는 데 전념하는 라이브러리인 [Text Generation Inference (TGI)](https://hf.co/docs/text-generation-inference)을 제공합니다. 이 라이브러리는 처리량 증가를 위한 지속적인 배칭과 다중 GPU 추론을 위한 텐서 병렬화와 같은 Transformers에 포함되지 않은 배포 지향 최적화 기능을 포함합니다.
+
+## 정적 kv-cache와 `torch.compile`[[static-kv-cache-and-torchcompile]]
+
+디코딩 중에 LLM은 각 입력 토큰에 대한 key-value(kv) 값을 계산합니다. LLM은 자기회귀(autoregressive)이기 때문에 생성된 출력이 현재 입력의 일부가 되어 매번 동일한 kv 값을 계산합니다. 이는 매번 동일한 kv 값을 다시 계산하기 때문에 효율적이지 않습니다.
+
+이를 최적화하기 위해, 이전 키(key)와 값(value)을 재계산하지 않고 저장하는 kv-cache를 사용할 수 있습니다. 그러나 kv-cache는 각 생성 단계에서 증가하며 동적이기 때문에 PyTorch 코드를 빠르고 최적화된 커널로 통합하는 강력한 최적화 도구인 [`torch.compile`](./perf_torch_compile)을 사용하는 데 제약이 있습니다.
+
+*정적 kv-cache*는 최댓값을 미리 할당하여 이 문제를 해결하여 `torch.compile`과 결합할 수 있게 합니다. 이를 통해 최대 4배의 속도 향상이 가능합니다. 속도 향상은 모델 크기(더 큰 모델은 속도 향상이 적음)와 하드웨어에 따라 다를 수 있습니다.
+
+> [!WARNING]
+현재 [Llama](./model_doc/llama2) 및 몇 가지 다른 모델만 정적 kv-cache와 `torch.compile`을 지원합니다. 실시간 모델 호환성 목록은 [이 이슈](https://github.com/huggingface/transformers/issues/28981)를 확인하십시오.
+
+작업의 복잡성에 따라 세 가지 방식의 정적 kv-cache 사용 방법이 있습니다:
+1. 기본 사용법: `generation_config`에서 플래그를 설정하기만 하면 됩니다(권장);
+2. 고급 사용법: 여러 번의 생성이나 맞춤형 생성 루프를 위해 캐시 객체를 처리합니다;
+3. 고급 사용법: 단일 그래프가 필요한 경우, 전체 `generate` 함수를 하나의 그래프로 컴파일합니다.
+
+올바른 탭을 선택하여 각 방법에 대한 추가 지침을 확인하세요.
+
+> [!TIP]
+> `torch.compile`을 사용할 때 어떤 전략을 사용하든, LLM 입력을 제한된 값 세트로 왼쪽에 패딩하면 모양과 관련된 재컴파일을 피할 수 있습니다. [`pad_to_multiple_of` tokenizer flag](https://huggingface.co/docs/transformers/main_classes/tokenizer#transformers.PreTrainedTokenizer.__call__.pad_to_multiple_of)가 유용할 것입니다!
+
+
+
+
+이 예제에서는 [Gemma](https://hf.co/google/gemma-2b) 모델을 사용해 보겠습니다. 필요한 작업은 다음과 같습니다:
+1. 모델의 `generation_config` 속성에 접근하여 `cache_implementation`을 "static"으로 설정합니다;
+2. 모델의 `forward` 패스를 정적 kv-cache와 함께 컴파일하기 위해 `torch.compile`을 호출합니다.
+
+이렇게 하면 끝입니다!
+
+```py
+from transformers import AutoTokenizer, AutoModelForCausalLM
+import torch
+import os
+os.environ["TOKENIZERS_PARALLELISM"] = "false" # 긴 경고 메시지를 방지하기 위해 설정 :)
+
+tokenizer = AutoTokenizer.from_pretrained("google/gemma-2b")
+model = AutoModelForCausalLM.from_pretrained("google/gemma-2b", device_map="auto")
+
+model.generation_config.cache_implementation = "static"
+
+model.forward = torch.compile(model.forward, mode="reduce-overhead", fullgraph=True)
+input_text = "The theory of special relativity states "
+input_ids = tokenizer(input_text, return_tensors="pt").to("cuda")
+
+outputs = model.generate(**input_ids)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['The theory of special relativity states 1. The speed of light is constant in all inertial reference']
+```
+
+`generate` 함수는 내부적으로 동일한 캐시 객체를 재사용하려고 시도하며, 이를 통해 각 호출 시 재컴파일의 필요성을 제거합니다. 재컴파일을 피하는 것은 `torch.compile`의 성능을 최대한 활용하는 데 매우 중요하며, 다음 사항에 유의해야 합니다:
+1. 배치 크기가 변경되거나 호출 간 최대 출력 길이가 증가하면 캐시를 다시 초기화해야 하며, 이로 인해 새로 컴파일을 해야 합니다;
+2. 컴파일된 함수의 첫 몇 번의 호출은 함수가 컴파일되는 동안 더 느립니다.
+
+> [!WARNING]
+> 다중 턴 대화와 같은 정적 캐시의 고급 사용을 위해서는, 캐시 객체를 [`~GenerationMixin.generate`] 외부에서 인스턴스화하고 조작하는 것을 권장합니다. 고급 사용법 탭을 참조하세요.
+
+
+
+
+[`StaticCache`] 객체는 `past_key_values` 인수로 모델의 [`~GenerationMixin.generate`] 함수에 전달할 수 있습니다. 이 객체는 캐시 내용을 유지하므로, 동적 캐시를 사용하는 것처럼 새로운 [`~GenerationMixin.generate`] 호출에 이를 전달하여 생성을 계속할 수 있습니다.
+
+```py
+from transformers import AutoTokenizer, AutoModelForCausalLM, StaticCache
+import torch
+import os
+os.environ["TOKENIZERS_PARALLELISM"] = "false" # 긴 경고 메시지를 방지하기 위해 설정 :)
+
+tokenizer = AutoTokenizer.from_pretrained("google/gemma-2b")
+model = AutoModelForCausalLM.from_pretrained("google/gemma-2b", device_map="auto")
+
+model.forward = torch.compile(model.forward, mode="reduce-overhead", fullgraph=True)
+input_text = "The theory of special relativity states "
+input_ids = tokenizer(input_text, return_tensors="pt").to("cuda")
+prompt_length = input_ids.input_ids.shape[1]
+model.generation_config.max_new_tokens = 16
+
+past_key_values = StaticCache(
+ config=model.config,
+ batch_size=1,
+ # 캐시를 재사용할 계획이 있는 경우, 모든 경우에 충분한 캐시 길이를 설정해야 합니다
+ max_cache_len=prompt_length+(model.generation_config.max_new_tokens*2),
+ device=model.device,
+ dtype=model.dtype
+)
+outputs = model.generate(**input_ids, past_key_values=past_key_values)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['The theory of special relativity states 1. The speed of light is constant in all inertial reference frames. 2']
+
+# 생성된 텍스트와 동일한 캐시 객체를 전달하여, 중단한 곳에서 생성을 계속합니다.
+# 다중 턴 대화의 경우, 생성된 텍스트에 새로운 사용자 입력을 추가할 수 있습니다.
+new_input_ids = outputs
+outputs = model.generate(new_input_ids, past_key_values=past_key_values)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['The theory of special relativity states 1. The speed of light is constant in all inertial reference frames. 2. The speed of light is constant in all inertial reference frames. 3.']
+```
+
+> [!TIP]
+> 동일한 [`StaticCache`] 객체를 새로운 프롬프트에 사용하려면, 호출 간에 `.reset()` 메서드를 사용하여 그 내용을 초기화하는 것이 좋습니다.
+
+더 깊이 들어가고 싶다면, [`StaticCache`] 객체를 모델의 `forward` 패스에 동일한 `past_key_values` 인수로 전달할 수도 있습니다. 이 전략을 사용하면, 현재 토큰과 이전에 생성된 토큰의 위치 및 캐시 위치를 바탕으로 다음 토큰을 디코딩하는 자체 함수를 작성할 수 있습니다.
+
+```py
+from transformers import LlamaTokenizer, LlamaForCausalLM, StaticCache, logging
+from transformers.testing_utils import CaptureLogger
+import torch
+
+prompts = [
+ "Simply put, the theory of relativity states that ",
+ "My favorite all time favorite condiment is ketchup.",
+]
+
+NUM_TOKENS_TO_GENERATE = 40
+torch_device = "cuda"
+
+tokenizer = LlamaTokenizer.from_pretrained("meta-llama/Llama-2-7b-hf", pad_token="", padding_side="right")
+model = LlamaForCausalLM.from_pretrained("meta-llama/Llama-2-7b-hf", device_map="sequential")
+inputs = tokenizer(prompts, return_tensors="pt", padding=True).to(model.device)
+
+def decode_one_tokens(model, cur_token, input_pos, cache_position, past_key_values):
+ logits = model(
+ cur_token,
+ position_ids=input_pos,
+ cache_position=cache_position,
+ past_key_values=past_key_values,
+ return_dict=False,
+ use_cache=True
+ )[0]
+ new_token = torch.argmax(logits[:, -1], dim=-1)[:, None]
+ return new_token
+```
+
+`StaticCache` 메서드를 사용하여 정적 kv-cache와 `torch.compile`을 활성화하려면 몇 가지 중요한 작업을 수행해야 합니다:
+1. 추론에 모델을 사용하기 전에 [`StaticCache`] 인스턴스를 초기화합니다. 여기서 최대 배치 크기와 시퀀스 길이와 같은 매개변수를 설정할 수 있습니다.
+2. 정적 kv-cache와 함께 순전파를 컴파일하기 위해 모델에 `torch.compile`을 호출합니다.
+3. [torch.backends.cuda.sdp_kernel](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention.html) 컨텍스트 관리자에서 `enable_math=True`를 설정하여 네이티브 PyTorch C++ 구현된 스케일된 점곱 어텐션(scaled dot product attention)을 활성화하여 추론 속도를 더욱 높입니다.
+
+```py
+batch_size, seq_length = inputs["input_ids"].shape
+with torch.no_grad():
+ past_key_values = StaticCache(
+ config=model.config, max_batch_size=2, max_cache_len=4096, device=torch_device, dtype=model.dtype
+ )
+ cache_position = torch.arange(seq_length, device=torch_device)
+ generated_ids = torch.zeros(
+ batch_size, seq_length + NUM_TOKENS_TO_GENERATE + 1, dtype=torch.int, device=torch_device
+ )
+ generated_ids[:, cache_position] = inputs["input_ids"].to(torch_device).to(torch.int)
+
+ logits = model(
+ **inputs, cache_position=cache_position, past_key_values=past_key_values,return_dict=False, use_cache=True
+ )[0]
+ next_token = torch.argmax(logits[:, -1], dim=-1)[:, None]
+ generated_ids[:, seq_length] = next_token[:, 0]
+
+ decode_one_tokens = torch.compile(decode_one_tokens, mode="reduce-overhead", fullgraph=True)
+ cache_position = torch.tensor([seq_length + 1], device=torch_device)
+ for _ in range(1, NUM_TOKENS_TO_GENERATE):
+ with torch.backends.cuda.sdp_kernel(enable_flash=False, enable_mem_efficient=False, enable_math=True):
+ next_token = decode_one_tokens(model, next_token.clone(), None, cache_position, past_key_values)
+ generated_ids[:, cache_position] = next_token.int()
+ cache_position += 1
+
+text = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+text
+['Simply put, the theory of relativity states that 1) the speed of light is constant, 2) the speed of light is the same for all observers, and 3) the laws of physics are the same for all observers.',
+ 'My favorite all time favorite condiment is ketchup. I love it on everything. I love it on my eggs, my fries, my chicken, my burgers, my hot dogs, my sandwiches, my salads, my p']
+```
+
+
+
+
+전체 `generate` 함수를 컴파일하는 것은 코드 측면에서 기본 사용법보다 더 간단합니다. `generate` 함수에 대해 `torch.compile`을 호출하여 전체 함수를 컴파일하면 됩니다. 정적 캐시의 사용을 지정할 필요는 없습니다. 정적 캐시는 호환되지만, 벤치마크에서는 동적 캐시(기본 설정)가 더 빠른 것으로 나타났습니다.
+
+```py
+from transformers import AutoTokenizer, AutoModelForCausalLM
+import torch
+import os
+os.environ["TOKENIZERS_PARALLELISM"] = "false" # 긴 경고 메시지를 방지하기 위해 설정 :)
+
+tokenizer = AutoTokenizer.from_pretrained("google/gemma-2b")
+model = AutoModelForCausalLM.from_pretrained("google/gemma-2b", device_map="auto")
+
+model.generate = torch.compile(model.generate, mode="reduce-overhead", fullgraph=True)
+input_text = "The theory of special relativity states "
+input_ids = tokenizer(input_text, return_tensors="pt").to("cuda")
+
+outputs = model.generate(**input_ids)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['The theory of special relativity states 1. The speed of light is constant in all inertial reference']
+```
+
+이 방법을 통해 모델의 forward 패스뿐만 아니라, 입력 준비, logit 처리기 작업 등을 포함한 모든 것을 컴파일합니다. 기본 사용 예제에 비해 `generate` 호출이 약간 더 빠를 수 있으며, 컴파일된 그래프는 더 특이한 하드웨어 장치나 사용 사례에 적합할 수 있습니다. 그러나 이 접근 방식을 사용하는 데는 몇 가지 큰 단점이 있습니다:
+1. 컴파일 속도가 훨씬 느립니다;
+2. `generate`의 모든 매개변수 설정은 `generation_config`를 통해서만 가능합니다;
+3. 많은 경고와 예외가 억제됩니다. -- 먼저 컴파일 되지 않은 형태로 테스트하는 것을 권장합니다;
+4. 현재 작업 중이지만 기능 제한이 심합니다(예: 작성 시점에서는 EOS 토큰이 선택되어도 생성이 중단되지 않습니다).
+
+
+
+
+## 추정 디코딩 [[speculative-decoding]]
+
+> [!TIP]
+> 보다 심층적인 설명을 원한다면, [Assisted Generation: a new direction toward low-latency text generation](https://hf.co/blog/assisted-generation) 블로그 게시물을 확인하십시오!
+
+자기 회귀의 또 다른 문제는 각 입력 토큰에 대해 순전파 중에 모델 가중치를 매번 로드해야 한다는 점입니다. 이는 수십억 개의 매개변수를 가진 LLM에는 느리고 번거롭습니다. 추정 디코딩(speculative decoding)은 더 작고 빠른 보조 모델을 사용하여 후보 토큰을 생성하고, 이를 큰 LLM이 단일 순전파에서 검증하여 이 속도 저하를 완화합니다. 검증된 토큰이 정확하다면, LLM은 본래 자체적으로 생성하는 것처럼 토큰을 얻을 수 있습니다. 전방 패스가 동일한 출력을 보장하기 때문에 정확도 저하가 없습니다.
+
+가장 큰 속도 향상을 얻기 위해, 보조 모델은 빠르게 토큰을 생성할 수 있도록 LLM보다 훨씬 작아야 합니다. 보조 모델과 LLM 모델은 토큰을 다시 인코딩하고 디코딩하지 않도록 동일한 토크나이저를 공유해야 합니다.
+
+> [!WARNING]
+> 추정 디코딩은 탐욕 검색과 샘플링 디코딩 전략에서만 지원되며, 배치 입력을 지원하지 않습니다.
+
+보조 모델을 로드하고 이를 [`~GenerationMixin.generate`] 메서드에 전달하여 추정 디코딩을 활성화하십시오.
+
+
+
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+import torch
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-1.3b")
+inputs = tokenizer("Einstein's theory of relativity states", return_tensors="pt").to(device)
+
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-1.3b").to(device)
+assistant_model = AutoModelForCausalLM.from_pretrained("facebook/opt-125m").to(device)
+outputs = model.generate(**inputs, assistant_model=assistant_model)
+tokenizer.batch_decode(outputs, skip_special_tokens=True)
+["Einstein's theory of relativity states that the speed of light is constant. "]
+```
+
+
+
+
+추정 샘플링 디코딩(speculative sampling decoding)을 위해, 보조 모델 외에도 [`~GenerationMixin.generate`] 메서드에 `do_sample` 및 `temperature` 매개변수를 추가하십시오.
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+import torch
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-1.3b")
+inputs = tokenizer("Einstein's theory of relativity states", return_tensors="pt").to(device)
+
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-1.3b").to(device)
+assistant_model = AutoModelForCausalLM.from_pretrained("facebook/opt-125m").to(device)
+outputs = model.generate(**inputs, assistant_model=assistant_model, do_sample=True, temperature=0.7)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+["Einstein's theory of relativity states that motion in the universe is not a straight line.\n"]
+```
+
+
+
+
+### 프롬프트 조회 디코딩 [[prompt-lookup-decoding]]
+
+프롬프트 조회 디코딩은 탐욕 검색과 샘플링과도 호환되는 추정 디코딩의 변형입니다. 프롬프트 조회는 요약과 같은 입력 기반 작업에 특히 잘 작동합니다. 여기서는 프롬프트와 출력 간에 종종 겹치는 단어가 있습니다. 이러한 겹치는 n-그램이 LLM 후보 토큰으로 사용됩니다.
+
+프롬프트 조회 디코딩을 활성화하려면 `prompt_lookup_num_tokens` 매개변수에 겹치는 토큰 수를 지정하십시오. 그런 다음 이 매개변수를 [`~GenerationMixin.generate`] 메서드에 전달할 수 있습니다.
+
+
+
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+import torch
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-1.3b")
+inputs = tokenizer("The second law of thermodynamics states", return_tensors="pt").to(device)
+
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-1.3b").to(device)
+assistant_model = AutoModelForCausalLM.from_pretrained("facebook/opt-125m").to(device)
+outputs = model.generate(**inputs, prompt_lookup_num_tokens=3)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['The second law of thermodynamics states that entropy increases with temperature. ']
+```
+
+
+
+
+샘플링과 함께 프롬프트 조회 디코딩을 사용하려면, [`~GenerationMixin.generate`] 메서드에 `do_sample` 및 `temperature` 매개변수를 추가하십시오.
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+import torch
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-1.3b")
+inputs = tokenizer("The second law of thermodynamics states", return_tensors="pt").to(device)
+
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-1.3b").to(device)
+outputs = model.generate(**inputs, prompt_lookup_num_tokens=3, do_sample=True, temperature=0.7)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+["The second law of thermodynamics states that energy cannot be created nor destroyed. It's not a"]
+```
+
+
+
+
+## 어텐션 최적화 [[attention-optimizations]]
+
+트랜스포머 모델의 알려진 문제는 셀프 어텐션 메커니즘이 입력 토큰 수와 함께 계산 및 메모리가 제곱으로 증가한다는 것입니다. 이 제한은 훨씬 더 긴 시퀀스를 처리하는 LLM에서는 더욱 커집니다. 이를 해결하기 위해 FlashAttention2 또는 PyTorch의 스케일된 점곱 어텐션을 사용해 보십시오. 이들은 더 메모리 효율적인 어텐션 구현으로 추론을 가속화할 수 있습니다.
+
+### FlashAttention-2 [[flashattention-2]]
+
+FlashAttention과 [FlashAttention-2](./perf_infer_gpu_one#flashattention-2)는 어텐션 계산을 더 작은 청크로 나누고 중간 읽기/쓰기 작업을 줄여 추론 속도를 높입니다. FlashAttention-2는 원래 FlashAttention 알고리즘을 개선하여 시퀀스 길이 차원에서도 병렬 처리를 수행하고 하드웨어에서 작업을 더 잘 분할하여 동기화 및 통신 오버헤드를 줄입니다.
+
+FlashAttention-2를 사용하려면 [`~PreTrainedModel.from_pretrained`] 메서드에서 `attn_implementation="flash_attention_2"`를 설정하십시오.
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quant_config = BitsAndBytesConfig(load_in_8bit=True)
+model = AutoModelForCausalLM.from_pretrained(
+ "google/gemma-2b",
+ quantization_config=quant_config,
+ torch_dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+)
+```
+
+### PyTorch 스케일된 점곱 어텐션(scaled dot product attention) [[pytorch-scaled-dot-product-attention]]
+
+스케일된 점곱 어텐션(SDPA)는 PyTorch 2.0에서 자동으로 활성화되며, FlashAttention, xFormers, PyTorch의 C++ 구현을 지원합니다. SDPA는 CUDA 백엔드를 사용하는 경우 가장 성능이 좋은 어텐션 알고리즘을 선택합니다. 다른 백엔드에서는 SDPA가 PyTorch C++ 구현으로 기본 설정됩니다.
+
+> [!TIP]
+> SDPA는 최신 PyTorch 버전이 설치되어 있으면 FlashAttention-2도 지원합니다.
+
+세 가지 어텐션 알고리즘 중 하나를 명시적으로 활성화하거나 비활성화하려면 [torch.backends.cuda.sdp_kernel](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention.html) 컨텍스트 관리자를 사용하십시오. 예를 들어 FlashAttention을 활성화하려면 `enable_flash=True`로 설정하십시오.
+
+```py
+import torch
+from transformers import AutoModelForCausalLM
+
+model = AutoModelForCausalLM.from_pretrained(
+ "google/gemma-2b",
+ torch_dtype=torch.bfloat16,
+)
+
+with torch.backends.cuda.sdp_kernel(enable_flash=True, enable_math=False, enable_mem_efficient=False):
+ outputs = model.generate(**inputs)
+```
+
+## 양자화 [[quantization]]
+
+양자화는 LLM 가중치를 더 낮은 정밀도로 저장하여 크기를 줄입니다. 이는 메모리 사용량을 줄이며 GPU 메모리에 제약이 있는 경우 추론을 위해 LLM을 로드하는 것을 더 용이하게 합니다. GPU가 충분하다면, 모델을 양자화할 필요는 없습니다. 추가적인 양자화 및 양자화 해제 단계로 인해 약간의 지연이 발생할 수 있기 때문입니다(AWQ 및 융합 AWQ 모듈 제외).
+
+> [!TIP]
+> 다양한 양자화 라이브러리(자세한 내용은 [Quantization](./quantization) 가이드를 참조하십시오)가 있습니다. 여기에는 Quanto, AQLM, VPTQ, AWQ 및 AutoGPTQ가 포함됩니다. 사용 사례에 가장 잘 맞는 라이브러리를 사용해 보십시오. 또한 AutoGPTQ와 bitsandbytes를 비교하는 [Overview of natively supported quantization schemes in 🤗 Transformers](https://hf.co/blog/overview-quantization-transformers) 블로그 게시물을 읽어보는 것을 추천합니다.
+
+아래의 모델 메모리 계산기를 사용하여 모델을 로드하는 데 필요한 메모리를 추정하고 비교해 보십시오. 예를 들어 [Mistral-7B-v0.1](https://huggingface.co/mistralai/Mistral-7B-v0.1)를 로드하는 데 필요한 메모리를 추정해 보십시오.
+
+
+
+Mistral-7B-v0.1을 반정밀도로 로드하려면 [`~transformers.AutoModelForCausalLM.from_pretrained`] 메서드에서 `torch_dtype` 매개변수를 `torch.bfloat16`으로 설정하십시오. 이 경우 13.74GB의 메모리가 필요합니다.
+
+```py
+from transformers import AutoTokenizer, AutoModelForCausalLM
+import torch
+
+model = AutoModelForCausalLM.from_pretrained(
+ "mistralai/Mistral-7B-v0.1", torch_dtype=torch.bfloat16, device_map="auto",
+)
+```
+
+추론을 위해 양자화된 모델(8비트 또는 4비트)을 로드하려면 [bitsandbytes](https://hf.co/docs/bitsandbytes)를 사용하고 `load_in_4bit` 또는 `load_in_8bit` 매개변수를 `True`로 설정하십시오. 모델을 8비트로 로드하는 데는 6.87GB의 메모리만 필요합니다.
+
+```py
+from transformers import AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig
+import torch
+
+quant_config = BitsAndBytesConfig(load_in_8bit=True)
+model = AutoModelForCausalLM.from_pretrained(
+ "mistralai/Mistral-7B-v0.1", quantization_config=quant_config, device_map="auto"
+)
+```
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/llm_tutorial.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/llm_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..d5e0bd356edd2e8589e1f70a3ca65809d09c6d72
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/llm_tutorial.md
@@ -0,0 +1,222 @@
+
+
+
+# 대규모 언어 모델로 생성하기 [[generation-with-llms]]
+
+[[open-in-colab]]
+
+LLM 또는 대규모 언어 모델은 텍스트 생성의 핵심 구성 요소입니다. 간단히 말하면, 주어진 입력 텍스트에 대한 다음 단어(정확하게는 토큰)를 예측하기 위해 훈련된 대규모 사전 훈련 변환기 모델로 구성됩니다. 토큰을 한 번에 하나씩 예측하기 때문에 새로운 문장을 생성하려면 모델을 호출하는 것 외에 더 복잡한 작업을 수행해야 합니다. 즉, 자기회귀 생성을 수행해야 합니다.
+
+자기회귀 생성은 몇 개의 초기 입력값을 제공한 후, 그 출력을 다시 모델에 입력으로 사용하여 반복적으로 호출하는 추론 과정입니다. 🤗 Transformers에서는 [`~generation.GenerationMixin.generate`] 메소드가 이 역할을 하며, 이는 생성 기능을 가진 모든 모델에서 사용 가능합니다.
+
+이 튜토리얼에서는 다음 내용을 다루게 됩니다:
+
+* LLM으로 텍스트 생성
+* 일반적으로 발생하는 문제 해결
+* LLM을 최대한 활용하기 위한 다음 단계
+
+시작하기 전에 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers bitsandbytes>=0.39.0 -q
+```
+
+
+## 텍스트 생성 [[generate-text]]
+
+[인과적 언어 모델링(causal language modeling)](tasks/language_modeling)을 목적으로 학습된 언어 모델은 일련의 텍스트 토큰을 입력으로 사용하고, 그 결과로 다음 토큰이 나올 확률 분포를 제공합니다.
+
+
+
+ "LLM의 전방 패스"
+
+
+LLM과 자기회귀 생성을 함께 사용할 때 핵심적인 부분은 이 확률 분포로부터 다음 토큰을 어떻게 고를 것인지입니다. 다음 반복 과정에 사용될 토큰을 결정하는 한, 어떠한 방법도 가능합니다. 확률 분포에서 가장 가능성이 높은 토큰을 선택하는 것처럼 간단할 수도 있고, 결과 분포에서 샘플링하기 전에 수십 가지 변환을 적용하는 것처럼 복잡할 수도 있습니다.
+
+
+
+ "자기회귀 생성은 확률 분포에서 다음 토큰을 반복적으로 선택하여 텍스트를 생성합니다."
+
+
+위에서 설명한 과정은 어떤 종료 조건이 충족될 때까지 반복적으로 수행됩니다. 모델이 시퀀스의 끝(EOS 토큰)을 출력할 때까지를 종료 조건으로 하는 것이 이상적입니다. 그렇지 않은 경우에는 미리 정의된 최대 길이에 도달했을 때 생성이 중단됩니다.
+
+모델이 예상대로 동작하기 위해선 토큰 선택 단계와 정지 조건을 올바르게 설정하는 것이 중요합니다. 이러한 이유로, 각 모델에는 기본 생성 설정이 잘 정의된 [`~generation.GenerationConfig`] 파일이 함께 제공됩니다.
+
+코드를 확인해봅시다!
+
+
+
+기본 LLM 사용에 관심이 있다면, 우리의 [`Pipeline`](pipeline_tutorial) 인터페이스로 시작하는 것을 추천합니다. 그러나 LLM은 양자화나 토큰 선택 단계에서의 미세한 제어와 같은 고급 기능들을 종종 필요로 합니다. 이러한 작업은 [`~generation.GenerationMixin.generate`]를 통해 가장 잘 수행될 수 있습니다. LLM을 이용한 자기회귀 생성은 자원을 많이 소모하므로, 적절한 처리량을 위해 GPU에서 실행되어야 합니다.
+
+
+
+먼저, 모델을 불러오세요.
+
+```python
+>>> from transformers import AutoModelForCausalLM
+
+>>> model = AutoModelForCausalLM.from_pretrained(
+... "mistralai/Mistral-7B-v0.1", device_map="auto", load_in_4bit=True
+... )
+```
+
+`from_pretrained` 함수를 호출할 때 2개의 플래그를 주목하세요:
+
+- `device_map`은 모델이 GPU로 이동되도록 합니다.
+- `load_in_4bit`는 리소스 요구 사항을 크게 줄이기 위해 [4비트 동적 양자화](main_classes/quantization)를 적용합니다.
+
+이 외에도 모델을 초기화하는 다양한 방법이 있지만, LLM을 처음 시작할 때 이 설정을 추천합니다.
+
+이어서 텍스트 입력을 [토크나이저](tokenizer_summary)으로 전처리하세요.
+
+```python
+>>> from transformers import AutoTokenizer
+>>> import torch
+
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1")
+>>> device = "cuda" if torch.cuda.is_available() else "cpu"
+>>> model_inputs = tokenizer(["A list of colors: red, blue"], return_tensors="pt").to(device)
+```
+
+`model_inputs` 변수에는 토큰화된 텍스트 입력과 함께 어텐션 마스크가 들어 있습니다. [`~generation.GenerationMixin.generate`]는 어텐션 마스크가 제공되지 않았을 경우에도 이를 추론하려고 노력하지만, 최상의 성능을 위해서는 가능하면 어텐션 마스크를 전달하는 것을 권장합니다.
+
+마지막으로 [`~generation.GenerationMixin.generate`] 메소드를 호출해 생성된 토큰을 얻은 후, 이를 출력하기 전에 텍스트 형태로 변환하세요.
+
+```python
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'A list of colors: red, blue, green, yellow, black, white, and brown'
+```
+
+이게 전부입니다! 몇 줄의 코드만으로 LLM의 능력을 활용할 수 있게 되었습니다.
+
+
+## 일반적으로 발생하는 문제 [[common-pitfalls]]
+
+[생성 전략](generation_strategies)이 많고, 기본값이 항상 사용 사례에 적합하지 않을 수 있습니다. 출력이 예상과 다를 때 흔히 발생하는 문제와 이를 해결하는 방법에 대한 목록을 만들었습니다.
+
+```py
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1")
+>>> tokenizer.pad_token = tokenizer.eos_token # Mistral has no pad token by default
+>>> model = AutoModelForCausalLM.from_pretrained(
+... "mistralai/Mistral-7B-v0.1", device_map="auto", load_in_4bit=True
+... )
+```
+
+### 생성된 출력이 너무 짧거나 길다 [[generated-output-is-too-shortlong]]
+
+[`~generation.GenerationConfig`] 파일에서 별도로 지정하지 않으면, `generate`는 기본적으로 최대 20개의 토큰을 반환합니다. `generate` 호출에서 `max_new_tokens`을 수동으로 설정하여 반환할 수 있는 새 토큰의 최대 수를 설정하는 것이 좋습니다. LLM(정확하게는 [디코더 전용 모델](https://huggingface.co/learn/nlp-course/chapter1/6?fw=pt))은 입력 프롬프트도 출력의 일부로 반환합니다.
+
+
+```py
+>>> model_inputs = tokenizer(["A sequence of numbers: 1, 2"], return_tensors="pt").to("cuda")
+
+>>> # By default, the output will contain up to 20 tokens
+>>> generated_ids = model.generate(**model_inputs, pad_token_id=tokenizer.eos_token_id)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'A sequence of numbers: 1, 2, 3, 4, 5'
+
+>>> # Setting `max_new_tokens` allows you to control the maximum length
+>>> generated_ids = model.generate(**model_inputs, pad_token_id=tokenizer.eos_token_id, max_new_tokens=50)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'A sequence of numbers: 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16,'
+```
+
+### 잘못된 생성 모드 [[incorrect-generation-mode]]
+
+기본적으로 [`~generation.GenerationConfig`] 파일에서 별도로 지정하지 않으면, `generate`는 각 반복에서 가장 확률이 높은 토큰을 선택합니다(그리디 디코딩). 하려는 작업에 따라 이 방법은 바람직하지 않을 수 있습니다. 예를 들어, 챗봇이나 에세이 작성과 같은 창의적인 작업은 샘플링이 적합할 수 있습니다. 반면, 오디오를 텍스트로 변환하거나 번역과 같은 입력 기반 작업은 그리디 디코딩이 더 적합할 수 있습니다. `do_sample=True`로 샘플링을 활성화할 수 있으며, 이 주제에 대한 자세한 내용은 이 [블로그 포스트](https://huggingface.co/blog/how-to-generate)에서 볼 수 있습니다.
+
+```python
+>>> # Set seed or reproducibility -- you don't need this unless you want full reproducibility
+>>> from transformers import set_seed
+>>> set_seed(0)
+
+>>> model_inputs = tokenizer(["I am a cat."], return_tensors="pt").to("cuda")
+
+>>> # LLM + greedy decoding = repetitive, boring output
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'I am a cat. I am a cat. I am a cat. I am a cat'
+
+>>> # With sampling, the output becomes more creative!
+>>> generated_ids = model.generate(**model_inputs, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'I am a cat.\nI just need to be. I am always.\nEvery time'
+```
+
+### 잘못된 패딩 [[wrong-padding-side]]
+
+LLM은 [디코더 전용](https://huggingface.co/learn/nlp-course/chapter1/6?fw=pt) 구조를 가지고 있어, 입력 프롬프트에 대해 지속적으로 반복 처리를 합니다. 입력 데이터의 길이가 다르면 패딩 작업이 필요합니다. LLM은 패딩 토큰에서 작동을 이어가도록 설계되지 않았기 때문에, 입력 왼쪽에 패딩이 추가 되어야 합니다. 그리고 어텐션 마스크도 꼭 `generate` 함수에 전달되어야 합니다!
+
+```python
+>>> # The tokenizer initialized above has right-padding active by default: the 1st sequence,
+>>> # which is shorter, has padding on the right side. Generation fails.
+>>> model_inputs = tokenizer(
+... ["1, 2, 3", "A, B, C, D, E"], padding=True, return_tensors="pt"
+... ).to("cuda")
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids[0], skip_special_tokens=True)[0]
+''
+
+>>> # With left-padding, it works as expected!
+>>> tokenizer = AutoTokenizer.from_pretrained("openlm-research/open_llama_7b", padding_side="left")
+>>> tokenizer.pad_token = tokenizer.eos_token # Llama has no pad token by default
+>>> model_inputs = tokenizer(
+... ["1, 2, 3", "A, B, C, D, E"], padding=True, return_tensors="pt"
+... ).to("cuda")
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'1, 2, 3, 4, 5, 6,'
+```
+
+
+
+## 추가 자료 [[further-resources]]
+
+자기회귀 생성 프로세스는 상대적으로 단순한 편이지만, LLM을 최대한 활용하려면 여러 가지 요소를 고려해야 하므로 쉽지 않을 수 있습니다. LLM에 대한 더 깊은 이해와 활용을 위한 다음 단계는 아래와 같습니다:
+
+
+### 고급 생성 사용 [[advanced-generate-usage]]
+
+1. [가이드](generation_strategies)는 다양한 생성 방법을 제어하는 방법, 생성 설정 파일을 설정하는 방법, 출력을 스트리밍하는 방법에 대해 설명합니다.
+2. [`~generation.GenerationConfig`]와 [`~generation.GenerationMixin.generate`], [generate-related classes](internal/generation_utils)를 참조해보세요.
+
+### LLM 리더보드 [[llm-leaderboards]]
+
+1. [Open LLM Leaderboard](https://huggingface.co/spaces/HuggingFaceH4/open_llm_leaderboard)는 오픈 소스 모델의 품질에 중점을 둡니다.
+2. [Open LLM-Perf Leaderboard](https://huggingface.co/spaces/optimum/llm-perf-leaderboard)는 LLM 처리량에 중점을 둡니다.
+
+### 지연 시간 및 처리량 [[latency-and-throughput]]
+
+1. 메모리 요구 사항을 줄이려면, 동적 양자화에 대한 [가이드](main_classes/quantization)를 참조하세요.
+
+### 관련 라이브러리 [[related-libraries]]
+
+1. [`text-generation-inference`](https://github.com/huggingface/text-generation-inference)는 LLM을 위한 실제 운영 환경에 적합한 서버입니다.
+2. [`optimum`](https://github.com/huggingface/optimum)은 특정 하드웨어 장치에서 LLM을 최적화하기 위해 🤗 Transformers를 확장한 것입니다.
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/llm_tutorial_optimization.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/llm_tutorial_optimization.md
new file mode 100644
index 0000000000000000000000000000000000000000..d43affd288fcd5e9b1589bbda634baa5dade67f3
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/llm_tutorial_optimization.md
@@ -0,0 +1,759 @@
+
+# 대규모 언어 모델의 속도 및 메모리 최적화 [[optimizing-llms-for-speed-and-memory]]
+
+[[open-in-colab]]
+
+GPT3/4, [Falcon](https://huggingface.co/tiiuae/falcon-40b), [Llama](https://huggingface.co/meta-llama/Llama-2-70b-hf)와 같은 대규모 언어 모델의 인간 중심 과제를 해결하는 능력이 빠르게 발전하고 있으며, 현대 지식 기반 산업에서 필수 도구로 자리잡고 있습니다. 그러나 이러한 모델을 실제 과제에 배포하는 것은 여전히 어려운 과제입니다.
+
+- 인간과 비슷한 텍스트 이해 및 생성 능력을 보이기 위해, 현재 대규모 언어 모델은 수십억 개의 매개변수로 구성되어야 합니다 (참조: [Kaplan et al](https://arxiv.org/abs/2001.08361), [Wei et. al](https://arxiv.org/abs/2206.07682)). 이는 추론을 위한 메모리 요구를 크게 증가시킵니다.
+- 많은 실제 과제에서 대규모 언어 모델은 방대한 맥락 정보를 제공받아야 합니다. 이는 모델이 추론 과정에서 매우 긴 입력 시퀀스를 처리할 수 있어야 한다는 것을 뜻합니다.
+
+이러한 과제의 핵심은 대규모 언어 모델의 계산 및 메모리 활용 능력을 증대시키는 데 있습니다. 특히 방대한 입력 시퀀스를 처리할 때 이러한 능력이 중요합니다.
+
+이 가이드에서는 효율적인 대규모 언어 모델 배포를 위한 효과적인 기법들을 살펴보겠습니다.
+
+1. **낮은 정밀도:** 연구에 따르면, [8비트와 4비트](./main_classes/quantization.md)와 같이 낮은 수치 정밀도로 작동하면 모델 성능의 큰 저하 없이 계산상의 이점을 얻을 수 있습니다.
+
+2. **플래시 어텐션:** 플래시 어텐션은 메모리 효율성을 높일 뿐만 아니라 최적화된 GPU 메모리 활용을 통해 효율성을 향상시키는 어텐션 알고리즘의 변형입니다.
+
+3. **아키텍처 혁신:** 추론 시 대규모 언어 모델은 주로 동일한 방식(긴 입력 맥락을 가진 자기회귀 텍스트 생성 방식)으로 배포되는데, 더 효율적인 추론을 가능하게 하는 특화된 모델 아키텍처가 제안되었습니다. 이러한 모델 아키텍처의 가장 중요한 발전으로는 [Alibi](https://arxiv.org/abs/2108.12409), [Rotary embeddings](https://arxiv.org/abs/2104.09864), [Multi-Query Attention (MQA)](https://arxiv.org/abs/1911.02150), [Grouped-Query-Attention (GQA)]((https://arxiv.org/abs/2305.13245))이 있습니다.
+
+이 가이드에서는 텐서의 관점에서 자기회귀 생성에 대한 분석을 제공합니다. 낮은 정밀도를 채택하는 것의 장단점을 논의하고, 최신 어텐션 알고리즘을 포괄적으로 탐구하며, 향상된 대규모 언어 모델 아키텍처에 대해 논합니다. 이 과정에서 각 기능의 개선 사항을 보여주는 실용적인 예제를 확인합니다.
+
+## 1. 낮은 정밀도 [[1-lower-precision]]
+
+대규모 언어 모델을 가중치 행렬과 벡터의 집합으로 보고, 텍스트 입력을 벡터의 시퀀스로 본다면, 대규모 언어 모델의 메모리 요구사항을 가장 잘 이해할 수 있습니다. 이어지는 내용에서 *가중치*는 모델의 모든 가중치 행렬과 벡터를 의미합니다.
+
+이 가이드를 작성하는 시점의 대규모 언어 모델은 최소 몇십억 개의 매개변수로 구성되어 있습니다. 각 매개변수는 `4.5689`와 같은 십진수로 이루어져 있으며, 보통 [float32](https://en.wikipedia.org/wiki/Single-precision_floating-point_format), [bfloat16](https://en.wikipedia.org/wiki/Bfloat16_floating-point_format) 또는 [float16](https://en.wikipedia.org/wiki/Half-precision_floating-point_format) 형식으로 저장됩니다. 이를 통해 대규모 언어 모델을 메모리에 로드하는 데 필요한 메모리의 요구사항을 쉽게 계산할 수 있습니다:
+
+> *X * 10억 개의 매개변수를 가진 모델의 가중치를 로드하려면 float32 정밀도에서 대략 4 * X GB의 VRAM이 필요합니다.*
+
+요즘에는 모델이 float32 정밀도로 훈련되는 경우는 드물고, 일반적으로 bfloat16 정밀도나 가끔 float16 정밀도로 훈련됩니다. 따라서 경험적으로 알아낸 법칙은 다음과 같습니다:
+
+> *X * 10억 개의 매개변수를 가진 모델의 가중치를 로드하려면 bfloat16/float16 정밀도에서 대략 2 * X GB의 VRAM이 필요합니다.*
+
+짧은 텍스트 입력(1024 토큰 미만)의 경우, 추론을 위한 메모리 요구 사항의 대부분은 가중치를 로드하는 데 필요한 메모리 요구 사항입니다. 따라서 지금은 추론을 위한 메모리 요구 사항이 모델의 가중치를 GPU VRAM에 로드하는 데 필요한 메모리 요구 사항과 같다고 가정합시다.
+
+모델을 bfloat16으로 로드하는 데 대략 얼마나 많은 VRAM이 필요한지 몇 가지 예를 들어보겠습니다:
+
+- **GPT3**는 2 \* 175 GB = **350 GB** VRAM이 필요합니다.
+- [**Bloom**](https://huggingface.co/bigscience/bloom)은 2 \* 176 GB = **352 GB** VRAM이 필요합니다.
+- [**Llama-2-70b**](https://huggingface.co/meta-llama/Llama-2-70b-hf)는 2 \* 70 GB = **140 GB** VRAM이 필요합니다.
+- [**Falcon-40b**](https://huggingface.co/tiiuae/falcon-40b)는 2 \* 40 GB = **80 GB** VRAM이 필요합니다.
+- [**MPT-30b**](https://huggingface.co/mosaicml/mpt-30b)는 2 * 30 GB = **60 GB** VRAM이 필요합니다.
+- [**bigcode/starcoder**](https://huggingface.co/bigcode/starcoder)는 2 * 15.5 GB = **31 GB** VRAM이 필요합니다.
+
+이 문서를 작성하는 시점에서, 현재 시장에서 가장 큰 GPU 칩은 80GB의 VRAM을 제공하는 A100과 H100입니다. 앞서 언급된 대부분의 모델들은 로드하기 위해서는 최소 80GB 이상의 용량을 필요로 하며, 따라서 [텐서 병렬 처리](https://huggingface.co/docs/transformers/perf_train_gpu_many#tensor-parallelism) 및/또는 [파이프라인 병렬 처리](https://huggingface.co/docs/transformers/perf_train_gpu_many#naive-model-parallelism-vertical-and-pipeline-parallelism)를 반드시 필요로 합니다.
+
+🤗 Transformers는 텐서 병렬 처리를 바로 지원하지 않습니다. 이는 모델 아키텍처가 특정 방식으로 작성되어야 하기 때문입니다. 텐서 병렬 처리를 지원하는 방식으로 모델을 작성하는 데 관심이 있다면 [the text-generation-inference library](https://github.com/huggingface/text-generation-inference/tree/main/server/text_generation_server/models/custom_modeling)를 참조해 보시기 바랍니다.
+
+기본적인 파이프라인 병렬 처리는 바로 지원됩니다. 이를 위해 단순히 모델을 `device="auto"`로 로드하면 [여기](https://huggingface.co/docs/accelerate/v0.22.0/en/concept_guides/big_model_inference)에 설명된 대로 사용 가능한 GPU에 모델의 서로 다른 레이어를 자동으로 배치합니다. 이것은 매우 효과적이긴 하지만 이러한 기본 파이프라인 병렬 처리는 GPU 유휴 문제를 해결하지 못한다는 점을 유의해야 합니다. 더 발전된 파이프라인 병렬 처리가 필요하며, 이에 대한 설명은 [여기](https://huggingface.co/docs/transformers/en/perf_train_gpu_many#naive-model-parallelism-vertical-and-pipeline-parallelism)에서 확인할 수 있습니다.
+
+80GB A100 GPU 8개를 가진 노드에 접근할 수 있다면, BLOOM을 다음과 같이 로드할 수 있습니다.
+
+```bash
+!pip install transformers accelerate bitsandbytes optimum
+```
+```python
+from transformers import AutoModelForCausalLM
+
+model = AutoModelForCausalLM.from_pretrained("bigscience/bloom", device_map="auto", pad_token_id=0)
+```
+
+`device_map="auto"`를 사용하면 모든 사용 가능한 GPU에 어텐션 레이어가 고르게 분산됩니다.
+
+이 가이드에서는 [bigcode/octocoder](https://huggingface.co/bigcode/octocoder)를 사용할 것입니다. 이 모델은 단일 40GB A100 GPU 장치에서 실행할 수 있습니다. 앞으로 적용할 모든 메모리 및 속도 최적화는 모델 또는 텐서 병렬 처리를 필요로 하는 다른 모델에도 동일하게 적용될 수 있습니다.
+
+모델이 bfloat16 정밀도로 로드되기 때문에, 위의 경험적으로 알아낸 법칙을 사용하면 `bigcode/octocoder`를 사용하여 추론을 실행하기 위한 메모리 요구 사항이 약 31GB VRAM일 것으로 예상됩니다. 한 번 시도해 보겠습니다.
+
+먼저 모델과 토크나이저를 로드한 다음, 둘 다 Transformers의 [파이프라인](https://huggingface.co/docs/transformers/main_classes/pipelines) 객체에 전달합니다.
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer, pipeline
+import torch
+
+model = AutoModelForCausalLM.from_pretrained("bigcode/octocoder", torch_dtype=torch.bfloat16, device_map="auto", pad_token_id=0)
+tokenizer = AutoTokenizer.from_pretrained("bigcode/octocoder")
+
+pipe = pipeline("text-generation", model=model, tokenizer=tokenizer)
+```
+
+```python
+prompt = "Question: Please write a function in Python that transforms bytes to Giga bytes.\n\nAnswer:"
+
+result = pipe(prompt, max_new_tokens=60)[0]["generated_text"][len(prompt):]
+result
+```
+
+**출력**:
+```
+Here is a Python function that transforms bytes to Giga bytes:\n\n```python\ndef bytes_to_giga_bytes(bytes):\n return bytes / 1024 / 1024 / 1024\n```\n\nThis function takes a single
+```
+
+좋습니다. 이제 결과를 직접 사용하여 바이트를 기가바이트로 변환할 수 있습니다.
+
+```python
+def bytes_to_giga_bytes(bytes):
+ return bytes / 1024 / 1024 / 1024
+```
+
+[`torch.cuda.max_memory_allocated`](https://pytorch.org/docs/stable/generated/torch.cuda.max_memory_allocated.html)를 호출하여 최대 GPU 메모리 할당을 측정해 보겠습니다.
+
+```python
+bytes_to_giga_bytes(torch.cuda.max_memory_allocated())
+```
+
+**출력**:
+```bash
+29.0260648727417
+```
+
+대략적으로 계산한 결과와 거의 일치합니다! 바이트에서 킬로바이트로 변환할 때 1000이 아닌 1024로 곱해야 하므로 숫자가 정확하지 않은 것을 알 수 있습니다. 따라서 대략적으로 계산할 때 공식은 "최대 X GB"으로 이해할 수 있습니다. 만약 우리가 모델을 float32 정밀도로 실행하려고 했다면 더 큰 크기인 64GB의 VRAM이 필요했을 것입니다.
+
+> 거의 모든 모델이 요즘 bfloat16으로 학습되므로, [GPU가 bfloat16을 지원](https://discuss.pytorch.org/t/bfloat16-native-support/117155/5)한다면 모델을 float32 정밀도로 실행할 이유가 없습니다. float32로 돌리는 모델은 학습할 때 사용했던 정밀도보다 더 나은 추론 결과를 제공하지 않습니다.
+
+모델 가중치가 어떤 정밀도 형식으로 Hub에 저장되어 있는지 확실하지 않은 경우, HuggingFace Hub에서 해당 체크포인트 config의 `"torch_dtype"`을 확인하면 됩니다, *예*를 들어 [여기](https://huggingface.co/meta-llama/Llama-2-7b-hf/blob/6fdf2e60f86ff2481f2241aaee459f85b5b0bbb9/config.json#L21)를 확인하세요. 모델을 `from_pretrained(..., torch_dtype=...)`로 로드할 때는 config에 명시된 정밀도 유형과 동일한 정밀도로 설정하는 것이 권장됩니다. 단, 원래 유형이 float32인 경우 추론을 위해 `float16` 또는 `bfloat16`을 둘 다 사용할 수 있습니다.
+
+이제 `flush(...)` 함수를 정의하여 모든 메모리를 해제하고, GPU 메모리의 최대 할당량을 정확하게 측정하도록 합시다.
+
+
+```python
+del pipe
+del model
+
+import gc
+import torch
+
+def flush():
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.reset_peak_memory_stats()
+```
+
+다음 실험을 위해 바로 호출해 봅시다.
+
+```python
+flush()
+```
+최근 버전의 accelerate 라이브러리에서는 `release_memory()`라는 유틸리티 메소드도 사용할 수 있습니다.
+
+```python
+from accelerate.utils import release_memory
+# ...
+
+release_memory(model)
+```
+
+만약 GPU에 32GB의 VRAM이 없다면 어떻게 될까요? 모델 가중치를 성능에 큰 손실 없이 8비트 또는 4비트로 양자화할 수 있다는 것이 밝혀졌습니다(참고: [Dettmers et al.](https://arxiv.org/abs/2208.07339)). 최근의 [GPTQ 논문](https://arxiv.org/abs/2210.17323) 에서는 모델을 3비트 또는 2비트로 양자화해도 성능 손실이 허용 가능한 수준임을 보여주었습니다🤯.
+
+너무 자세한 내용은 다루지 않고 설명하자면, 양자화는 가중치의 정밀도를 줄이면서 모델의 추론 결과를 가능한 한 정확하게(즉, bfloat16과 최대한 가깝게) 유지하려고 합니다. 양자화는 특히 텍스트 생성에 잘 작동하는데, 이는 우리가 *가장 가능성 있는 다음 토큰 집합*을 선택하는 것에 초점을 두고 있기 때문이며, 다음 토큰의 *logit* 분포값을 정확하게 예측할 필요는 없기 때문입니다. 핵심은 다음 토큰 *logit* 분포가 대략적으로 동일하게 유지되어 `argmax` 또는 `topk` 연산이 동일한 결과를 제공하는 것입니다.
+
+다양한 양자화 기법이 존재하지만, 자세히 다루지는 않을 것입니다. 일반적으로 모든 양자화 기법은 다음과 같이 작동합니다:
+
+- 1. 모든 가중치를 목표 정밀도로 양자화합니다.
+- 2. 양자화된 가중치를 로드하고, bfloat16 정밀도의 입력 벡터 시퀀스를 모델에 전달합니다.
+- 3. 가중치를 동적으로 bfloat16으로 반대로 양자화(dequantize)하여 입력 벡터와 함께 bfloat16 정밀도로 계산을 수행합니다.
+
+간단히 말해서, *입력-가중치 행렬* 곱셈은, \\( X \\)가 *입력*, \\( W \\)가 가중치 행렬, \\( Y \\)가 출력인 경우 다음과 같습니다:
+
+$$ Y = X * W $$
+
+위 공식이 다음과 같이 변경됩니다
+
+$$ Y = X * \text{dequantize}(W) $$
+
+모든 행렬 곱셈에 대해 위와 같이 수행됩니다. 입력이 네트워크 그래프를 통과하면서 모든 가중치 행렬에 대해 역양자화(dequantization)와 재양자화(re-quantization)가 순차적으로 수행됩니다.
+
+따라서, 양자화된 가중치를 사용할 때 추론 시간이 감소하지 **않고** 오히려 증가하는 경우가 많습니다. 이제 이론은 충분하니 실제로 시도해 봅시다! Transformers를 사용하여 가중치를 양자화하려면 [`bitsandbytes`](https://github.com/TimDettmers/bitsandbytes) 라이브러리가 설치되어 있는지 확인해야 합니다.
+
+```bash
+!pip install bitsandbytes
+```
+
+그런 다음 `from_pretrained`에 `load_in_8bit=True` 플래그를 추가하여 8비트 양자화로 모델을 로드할 수 있습니다.
+
+```python
+model = AutoModelForCausalLM.from_pretrained("bigcode/octocoder", load_in_8bit=True, pad_token_id=0)
+```
+
+이제 예제를 다시 실행하고 메모리 사용량을 측정해 봅시다.
+
+```python
+pipe = pipeline("text-generation", model=model, tokenizer=tokenizer)
+
+result = pipe(prompt, max_new_tokens=60)[0]["generated_text"][len(prompt):]
+result
+```
+
+**출력**:
+```
+Here is a Python function that transforms bytes to Giga bytes:\n\n```python\ndef bytes_to_giga_bytes(bytes):\n return bytes / 1024 / 1024 / 1024\n```\n\nThis function takes a single
+```
+
+좋습니다. 정확도 손실 없이 이전과 동일한 결과를 얻고 있습니다! 이번에는 사용된 메모리 양을 확인해 봅시다.
+
+```python
+bytes_to_giga_bytes(torch.cuda.max_memory_allocated())
+```
+
+**출력**:
+```
+15.219234466552734
+```
+
+훨씬 적네요! 메모리 사용량이 15GB를 조금 넘는 수준으로 줄어들어 4090과 같은 소비자용 GPU에서도 이 모델을 실행할 수 있습니다. 메모리 효율성에서 매우 큰 향상을 보이고 있으며 모델 출력의 품질 저하도 거의 없습니다. 그러나 추론 중에 약간의 속도 저하가 발생한 것을 확인할 수 있습니다.
+
+
+모델을 삭제하고 메모리를 다시 초기화합니다.
+
+```python
+del model
+del pipe
+```
+
+```python
+flush()
+```
+
+이제 4비트 양자화가 제공하는 최대 GPU 메모리 사용량을 확인해 봅시다. 4비트로 모델을 양자화하려면 이전과 동일한 API를 사용하되 이번에는 `load_in_8bit=True` 대신 `load_in_4bit=True`를 전달하면 됩니다.
+
+```python
+model = AutoModelForCausalLM.from_pretrained("bigcode/octocoder", load_in_4bit=True, low_cpu_mem_usage=True, pad_token_id=0)
+
+pipe = pipeline("text-generation", model=model, tokenizer=tokenizer)
+
+result = pipe(prompt, max_new_tokens=60)[0]["generated_text"][len(prompt):]
+result
+```
+
+**출력**:
+```
+Here is a Python function that transforms bytes to Giga bytes:\n\n```\ndef bytes_to_gigabytes(bytes):\n return bytes / 1024 / 1024 / 1024\n```\n\nThis function takes a single argument
+```
+
+바로 전 코드 스니펫에서 `python`만 누락되고, 이 전과 거의 동일한 출력 텍스트를 보고 있습니다. 이제 얼마나 많은 메모리가 필요했는지 확인해 봅시다.
+
+```python
+bytes_to_giga_bytes(torch.cuda.max_memory_allocated())
+```
+
+**출력**:
+```
+9.543574333190918
+```
+
+9.5GB밖에 되지 않습니다! 150억 개 이상의 파라미터를 가진 모델인 것을 감안하면 매우 적은 양입니다.
+
+여기서는 모델의 정확도 저하가 거의 없음을 확인할 수 있지만, 실제로는 4비트 양자화를 8비트 양자화나 `bfloat16`를 사용한 추론 결과와 비교하면 결과가 다를 수 있습니다. 사용자가 직접 시도해 보는 것이 좋겠습니다.
+
+또한 4비트 양자화에 사용된 더 공격적인 양자화 방법으로 인해 추론 시 \\( \text{quantize} \\)와 \\( \text{dequantize} \\) 과정이 더 오래 걸리므로 여기서도 8비트 양자화와 비교하여 추론 속도가 약간 느려졌음을 유의하세요.
+
+```python
+del model
+del pipe
+```
+```python
+flush()
+```
+
+전체적으로 OctoCoder를 8비트 정밀도로 실행하면 필요한 GPU VRAM이 32GB에서 15GB로 줄어들었고, 4비트 정밀도로 모델을 실행하면 필요한 GPU VRAM이 9GB로 더 줄어드는 것을 확인했습니다.
+
+4비트 양자화는 RTX3090, V100, T4와 같은 GPU에서 모델을 실행할 수 있게 해주며, 이는 대부분의 사람들이 접근할 수 있는 GPU입니다.
+
+양자화에 대한 더 많은 정보를 확인하고 4비트보다 더 적은 GPU VRAM 메모리로 모델을 양자화하거나, 더 많은 양자화 관련 정보를 보려면 [`AutoGPTQ`](https://huggingface.co/docs/transformers/main/en/main_classes/quantization#autogptq-integration%60) 구현을 참조하는 것을 추천합니다.
+
+> 결론적으로, 모델 양자화는 향상된 메모리 효율성과 모델 정확성 간의 균형을 맞추는 것이며, 경우에 따라 추론 시간에도 영향을 미칠 수 있습니다.
+
+실제 사례에서 GPU 메모리가 충분하다면, 양자화를 고려할 필요가 없습니다. 그러나 많은 GPU는 양자화 없이 대규모 언어 모델을 실행할 수 없으며, 이 경우 4비트 및 8비트 양자화가 매우 유용한 도구입니다.
+
+사용과 관련한 더 자세한 정보는 [트랜스포머 양자화 문서](https://huggingface.co/docs/transformers/main_classes/quantization#general-usage)를 참고하는 것을 강력히 추천합니다. 다음으로, 더 나은 알고리즘과 개선된 모델 아키텍처를 사용하여 계산 및 메모리 효율성을 향상시키는 방법을 살펴보겠습니다.
+
+## 2. 플래시 어텐션 [[2-flash-attention]]
+
+오늘날의 최고 성능을 자랑하는 대규모 언어 모델은 대체로 피드포워드 레이어(feed-forward layer), 활성화 레이어(activation layer), 레이어 정규화 레이어(layer normalization layer), 그리고 가장 중요한 셀프 어텐션 레이어(self-attention layer)로 구성된 아키텍처를 공유하고 있습니다.
+
+셀프 어텐션 레이어는 입력 토큰 간의 문맥적 관계를 이해할 수 있게 해 주기 때문에 대규모 언어 모델의 핵심 요소입니다.
+하지만 셀프 어텐션 레이어의 최대 GPU 메모리 소비는 입력 토큰의 수(이하 \\( N \\)으로 표기)와 함께 계산 및 메모리 복잡성이 *2차적*으로 증가합니다. 입력 시퀀스가 짧은 경우(최대 1000개)에는 크게 눈에 띄지 않지만, 더 긴 입력 시퀀스(약 16000개)에서는 심각한 문제가 됩니다.
+
+자세히 한 번 들여다 봅시다. 길이 \\( N \\)의 입력 \\( \mathbf{X} \\)에 대한 셀프 어텐션 레이어의 출력 \\( \mathbf{O} \\)을 계산하는 공식은 다음과 같습니다:
+
+$$ \textbf{O} = \text{Attn}(\mathbf{X}) = \mathbf{V} \times \text{Softmax}(\mathbf{QK}^T) \text{ with } \mathbf{Q} = \mathbf{W}_q \mathbf{X}, \mathbf{V} = \mathbf{W}_v \mathbf{X}, \mathbf{K} = \mathbf{W}_k \mathbf{X} $$
+
+\\( \mathbf{X} = (\mathbf{x}1, ... \mathbf{x}{N}) \\)는 어텐션 레이어의 입력 시퀀스입니다. 프로젝션 \\( \mathbf{Q} \\)와 \\( \mathbf{K} \\)는 각각 \\( N \\)개의 벡터로 구성되며, 그 결과 \\( \mathbf{QK}^T \\)의 크기는 \\( N^2 \\)가 됩니다.
+
+대규모 언어 모델은 일반적으로 여러 개의 어텐션 헤드를 가지고 있어 여러 개의 셀프 어텐션 계산을 병렬로 수행합니다. 대규모 언어 모델이 40개의 어텐션 헤드를 가지고 bfloat16 정밀도로 실행된다고 가정하면, \\( \mathbf{QK^T} \\) 행렬을 저장하는 데 필요한 메모리를 \\( 40 * 2 * N^2 \\) 바이트로 계산할 수 있습니다. \\( N=1000 \\)일 때는 약 50MB의 VRAM만 필요하지만, \\( N=16000 \\)일 때는 19GB의 VRAM이 필요하며, \\( N=100,000 \\)일 때는 \\( \mathbf{QK^T} \\) 행렬을 저장하기 위해 거의 1TB의 VRAM이 필요합니다.
+
+요약하자면, 기본 셀프 어텐션 알고리즘은 큰 입력 컨텍스트에 대해 매우 과도한 메모리 사용을 요구하게 됩니다.
+
+대규모 언어 모델의 텍스트 이해 및 생성 능력이 개선되면서 점점 더 복잡한 작업에 사용되고 있습니다. 한때 몇 문장의 번역이나 요약을 처리하던 모델이 이제는 전체 페이지를 처리해야 하게 되면서 광범위한 입력 길이를 처리할 수 있는 능력이 요구되고 있습니다.
+
+어떻게 하면 큰 입력 길이에 대한 과도한 메모리 요구를 없앨 수 있을까요? \\( QK^T \\) 행렬을 제거하는 새로운 셀프 어텐션 메커니즘을 계산하는 방법이 필요합니다. [Tri Dao et al.](https://arxiv.org/abs/2205.14135)은 바로 이러한 새로운 알고리즘을 개발하였고, 그것이 **플래시 어텐션(Flash Attention)**입니다.
+
+간단히 말해, 플래시 어텐션은 \\(\mathbf{V} \times \text{Softmax}(\mathbf{QK}^T\\)) 계산을 분할하는데, 여러 번의 소프트맥스 계산을 반복하면서 작은 청크 단위로 출력을 계산합니다:
+
+$$ \textbf{O}_i \leftarrow s^a_{ij} * \textbf{O}_i + s^b_{ij} * \mathbf{V}_{j} \times \text{Softmax}(\mathbf{QK}^T_{i,j}) \text{ for multiple } i, j \text{ iterations} $$
+
+여기서 \\( s^a_{ij} \\)와 \\( s^b_{ij} \\)는 각 \\( i \\)와 \\( j \\)에 대해 계산되는 소프트맥스 정규화 통계량입니다.
+
+플래시 어텐션의 전체 알고리즘은 더 복잡하며, 본 가이드의 범위를 벗어나기 때문에 크게 단순화하였습니다. 여러분은 잘 작성된 [Flash Attention paper](https://arxiv.org/abs/2205.14135) 논문을 참조하여 더 자세한 내용을 확인해 보시기 바랍니다.
+
+주요 요점은 다음과 같습니다:
+
+> 소프트맥스 정규화 통계량과 몇 가지 스마트한 수학적 방법을 사용함으로써, 플래시 어텐션은 기본 셀프 어텐션 레이어와 **숫자적으로 동일한** 출력을 제공하고 메모리 비용은 \\( N \\)에 따라 선형적으로만 증가합니다.
+
+공식을 보면, 플래시 어텐션이 더 많은 계산을 필요로 하기 때문에 기본 셀프 어텐션 공식보다 훨씬 느릴 것이라고 생각할 수 있습니다. 실제로 플래시 어텐션은 소프트맥스 정규화 통계량을 지속적으로 다시 계산해야 하기 때문에 일반 어텐션보다 더 많은 FLOP이 필요합니다. (더 자세한 내용은 [논문](https://arxiv.org/abs/2205.14135)을 참조하세요)
+
+> 그러나 플래시 어텐션은 기본 어텐션보다 추론 속도가 훨씬 빠릅니다. 이는 GPU의 느리고 고대역폭 메모리(VRAM)의 사용량을 크게 줄이고 대신 빠른 온칩 메모리(SRAM)에 집중할 수 있기 때문입니다.
+
+본질적으로, 플래시 어텐션의 모든 중간 단계의 쓰기 및 읽기 작업은 느린 VRAM 메모리에 접근하지 않고 빠른 *온칩* SRAM 메모리를 사용하여 출력 벡터 \\( \mathbf{O} \\)를 계산할 수 있도록 합니다.
+
+현실적으로 플래시 어텐션이 사용 가능한 경우 이를 **사용하지 않을** 이유는 전혀 없습니다. 이 알고리즘은 수학적으로 동일한 출력을 제공하며, 더 빠르고 메모리 효율적입니다.
+
+실제 예를 살펴보겠습니다.
+
+우리의 OctoCoder 모델은 이제 *시스템 프롬프트*가 포함된 훨씬 더 긴 입력 프롬프트를 받게 됩니다. 시스템 프롬프트는 대규모 언어 모델을 사용자의 작업에 맞춘 더 나은 어시스턴트로 유도하는 데 사용됩니다. 다음 예제에서는 OctoCoder를 더 나은 코딩 어시스턴트로 만들기 위한 시스템 프롬프트를 사용합니다.
+
+```python
+system_prompt = """Below are a series of dialogues between various people and an AI technical assistant.
+The assistant tries to be helpful, polite, honest, sophisticated, emotionally aware, and humble but knowledgeable.
+The assistant is happy to help with code questions and will do their best to understand exactly what is needed.
+It also tries to avoid giving false or misleading information, and it caveats when it isn't entirely sure about the right answer.
+That said, the assistant is practical really does its best, and doesn't let caution get too much in the way of being useful.
+
+The Starcoder models are a series of 15.5B parameter models trained on 80+ programming languages from The Stack (v1.2) (excluding opt-out requests).
+The model uses Multi Query Attention, was trained using the Fill-in-the-Middle objective, and with 8,192 tokens context window for a trillion tokens of heavily deduplicated data.
+
+-----
+
+Question: Write a function that takes two lists and returns a list that has alternating elements from each input list.
+
+Answer: Sure. Here is a function that does that.
+
+def alternating(list1, list2):
+ results = []
+ for i in range(len(list1)):
+ results.append(list1[i])
+ results.append(list2[i])
+ return results
+
+Question: Can you write some test cases for this function?
+
+Answer: Sure, here are some tests.
+
+assert alternating([10, 20, 30], [1, 2, 3]) == [10, 1, 20, 2, 30, 3]
+assert alternating([True, False], [4, 5]) == [True, 4, False, 5]
+assert alternating([], []) == []
+
+Question: Modify the function so that it returns all input elements when the lists have uneven length. The elements from the longer list should be at the end.
+
+Answer: Here is the modified function.
+
+def alternating(list1, list2):
+ results = []
+ for i in range(min(len(list1), len(list2))):
+ results.append(list1[i])
+ results.append(list2[i])
+ if len(list1) > len(list2):
+ results.extend(list1[i+1:])
+ else:
+ results.extend(list2[i+1:])
+ return results
+
+-----
+"""
+```
+시연을 위해 시스템 프롬프트를 10번 중복하여 증가시켜 플래시 어텐션의 메모리 절약 효과를 관찰할 수 있을 만큼 입력 길이를 충분히 길게 만듭니다. 원래의 텍스트 프롬프트를 다음과 같이 추가합니다. `"Question: Please write a function in Python that transforms bytes to Giga bytes.\n\nAnswer: Here"`
+
+```python
+long_prompt = 10 * system_prompt + prompt
+```
+
+모델을 다시 bfloat16 정밀도로 인스턴스화합니다.
+
+```python
+model = AutoModelForCausalLM.from_pretrained("bigcode/octocoder", torch_dtype=torch.bfloat16, device_map="auto")
+tokenizer = AutoTokenizer.from_pretrained("bigcode/octocoder")
+
+pipe = pipeline("text-generation", model=model, tokenizer=tokenizer)
+```
+
+이제 플래시 어텐션을 *사용하지 않고* 이전과 동일하게 모델을 실행하여 최대 GPU 메모리 요구량과 추론 시간을 측정해 봅시다.
+
+```python
+import time
+
+start_time = time.time()
+result = pipe(long_prompt, max_new_tokens=60)[0]["generated_text"][len(long_prompt):]
+
+print(f"Generated in {time.time() - start_time} seconds.")
+result
+```
+
+**출력**:
+```
+Generated in 10.96854019165039 seconds.
+Sure. Here is a function that does that.\n\ndef bytes_to_giga(bytes):\n return bytes / 1024 / 1024 / 1024\n\nAnswer: Sure. Here is a function that does that.\n\ndef
+````
+
+이전과 동일한 출력을 얻고 있지만, 이번에는 모델이 답변을 여러 번 반복하여 60개의 토큰이 잘릴 때까지 계속됩니다. 시연을 위해 시스템 프롬프트를 10번 반복했기 때문에 모델이 스스로 반복하도록 유도한 결과입니다. 이는 놀라운 일이 아닙니다.
+
+**참고** 실제 응용에서는 시스템 프롬프트를 10번 반복할 필요가 없습니다. 한 번만 사용하면 충분합니다!
+
+최대 GPU 메모리 요구량을 측정해 봅시다.
+
+```python
+bytes_to_giga_bytes(torch.cuda.max_memory_allocated())
+```
+
+**출력**:
+```bash
+37.668193340301514
+```
+
+보시다시피 최대 GPU 메모리 요구량이 처음보다 상당히 높아졌습니다. 이는 주로 입력 시퀀스가 길어졌기 때문입니다. 또한 생성 시간이 이제 1분을 넘어갑니다.
+
+다음 실험을 위해 `flush()`를 호출하여 GPU 메모리를 초기화합니다.
+
+```python
+flush()
+```
+
+비교를 위해, 동일한 기능을 실행하되 플래시 어텐션을 활성화해 보겠습니다.
+이를 위해 모델을 [BetterTransformer](https://huggingface.co/docs/optimum/bettertransformer/overview)로 변환하고, 이를 통해 PyTorch의 [SDPA self-attention](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention)을 활성화하면 플래시 어텐션을 사용할 수 있습니다.
+
+```python
+model.to_bettertransformer()
+```
+
+이제 이전과 동일한 코드 스니펫을 실행하면, 내부적으로 Transformers가 플래시 어텐션을 사용할 것입니다.
+
+```py
+start_time = time.time()
+with torch.backends.cuda.sdp_kernel(enable_flash=True, enable_math=False, enable_mem_efficient=False):
+ result = pipe(long_prompt, max_new_tokens=60)[0]["generated_text"][len(long_prompt):]
+
+print(f"Generated in {time.time() - start_time} seconds.")
+result
+```
+
+**출력**:
+```
+Generated in 3.0211617946624756 seconds.
+ Sure. Here is a function that does that.\n\ndef bytes_to_giga(bytes):\n return bytes / 1024 / 1024 / 1024\n\nAnswer: Sure. Here is a function that does that.\n\ndef
+```
+
+이전과 동일한 결과를 얻었지만, 플래시 어텐션 덕분에 매우 큰 속도 향상을 관찰할 수 있습니다.
+
+메모리 소비량을 마지막으로 한 번 더 측정해 봅시다.
+
+```python
+bytes_to_giga_bytes(torch.cuda.max_memory_allocated())
+```
+
+**출력**:
+```
+32.617331981658936
+```
+
+그리고 우리는 처음에 보았던 GPU 메모리 요구량인 29GB로 돌아왔습니다.
+
+플래시 어텐션을 사용하여 매우 긴 입력 시퀀스를 전달할 때 처음에 짧은 입력 시퀀스를 전달했을 때와 비교하여 약 100MB 정도의 GPU 메모리를 더 사용한다는 것을 관찰할 수 있습니다.
+
+```py
+flush()
+```
+
+플래시 어텐션 사용에 대한 자세한 정보는 [이 문서 페이지](https://huggingface.co/docs/transformers/en/perf_infer_gpu_one#flashattention-2)를 참조해 주세요.
+
+## 3. 아키텍처 혁신 [[3-architectural-innovations]]
+
+지금까지 우리는 계산 및 메모리 효율성을 개선하기 위해 다음을 살펴보았습니다:
+
+- 가중치를 낮은 정밀도 형식으로 변환
+- 셀프 어텐션 알고리즘을 보다 더 메모리 및 계산 효율적인 버전으로 교체
+
+이제 긴 텍스트 입력이 필요한 작업에 가장 효과적이고 효율적인 대규모 언어 모델 아키텍처로 변경하는 방법을 살펴보겠습니다. 작업의 예시는 다음과 같습니다:
+- 검색 증강 질의 응답
+- 요약
+- 채팅
+
+*채팅*을 위해서는 대규모 언어 모델이 긴 텍스트 입력을 처리하는 것뿐만 아니라 사용자와 어시스턴트 간의 대화도 효율적으로 처리할 수 있어야 합니다(예: ChatGPT).
+
+한번 학습된 후에는 대규모 언어 모델의 기본 아키텍처를 변경하기 어렵기 때문에, 대규모 언어 모델의 작업에 대한 고려를 미리 하고 이에 따라 모델의 아키텍처를 최적화하는 것이 중요합니다. 긴 입력 시퀀스에 대해 메모리 또는 성능의 병목 현상을 빠르게 발생시키는 모델 아키텍처의 중요한 두 가지 구성 요소가 있습니다.
+
+- 위치 임베딩
+- 키-값 캐시
+
+각 구성 요소를 더 자세히 살펴보겠습니다.
+
+### 3.1 대규모 언어 모델의 위치 임베딩 개선 [[31-improving-positional-embeddings-of-llms]]
+
+셀프 어텐션은 각 토큰을 서로의 토큰과 연관시킵니다.
+예를 들어, 텍스트 입력 시퀀스 *"Hello", "I", "love", "you"*의 \\( \text{Softmax}(\mathbf{QK}^T) \\) 행렬은 다음과 같을 수 있습니다:
+
+
+
+각 단어 토큰은 다른 모든 단어 토큰에 주의를 기울이는 확률 질량을 부여받아 모든 다른 단어 토큰과 관계를 맺게 됩니다. 예를 들어, 단어 *"love"*는 단어 *"Hello"*에 5%, *"I"*에 30%, 그리고 자신에게 65%의 주의를 기울입니다.
+
+셀프 어텐션 기반 대규모 언어 모델이 위치 임베딩이 없는 경우 텍스트 입력의 위치를 이해하는 데 큰 어려움을 겪을 것입니다. 이는 \\( \mathbf{QK}^T \\)에 의해 계산된 확률 점수가 상대적 위치 거리에 상관없이 각 단어 토큰을 다른 모든 단어 토큰과 \\( O(1) \\) 계산으로 연관시키기 때문입니다. 따라서 위치 임베딩이 없는 대규모 언어 모델은 각 토큰이 다른 모든 토큰과 동일한 거리에 있는 것으로 나타나기 때문에, *"Hello I love you"*와 *"You love I hello"*를 구분하는 것이 매우 어렵습니다.
+
+대규모 언어 모델이 문장의 순서를 이해하려면 추가적인 *단서*가 필요하며, 이는 일반적으로 *위치 인코딩* (또는 *위치 임베딩*이라고도 함)의 형태로 적용됩니다.
+위치 인코딩은 각 토큰의 위치를 숫자 표현으로 인코딩하여 대규모 언어 모델이 문장의 순서를 더 잘 이해할 수 있도록 도와줍니다.
+
+[*Attention Is All You Need*](https://arxiv.org/abs/1706.03762) 논문의 저자들은 사인 함수 기반의 위치 임베딩 \\( \mathbf{P} = \mathbf{p}_1, \ldots, \mathbf{p}_N \\)을 도입했습니다. 각 벡터 \\( \mathbf{p}_i \\)는 위치 \\( i \\)의 사인 함수로 계산됩니다. 위치 인코딩은 입력 시퀀스 벡터에 단순히 더해져 \\( \mathbf{\hat{X}} = \mathbf{\hat{x}}_1, \ldots, \mathbf{\hat{x}}_N \\) = \\( \mathbf{x}_1 + \mathbf{p}_1, \ldots, \mathbf{x}_N + \mathbf{p}_N \\) 모델이 문장 순서를 더 잘 학습할 수 있도록 합니다.
+
+고정된 위치 임베딩 대신 [Devlin et al.](https://arxiv.org/abs/1810.04805)과 같은 다른 연구자들은 학습된 위치 인코딩을 사용했습니다. 이 경우 위치 임베딩 \\( \mathbf{P} \\)은 학습 중에 사용됩니다.
+
+사인 함수 및 학습된 위치 임베딩은 문장 순서를 대규모 언어 모델에 인코딩하는 주요 방법이었지만, 이러한 위치 인코딩과 관련된 몇 가지 문제가 발견되었습니다:
+
+ 1. 사인 함수와 학습된 위치 임베딩은 모두 절대 위치 임베딩으로, 각 위치 ID \\( 0, \ldots, N \\)에 대해 고유한 임베딩을 인코딩합니다. [Huang et al.](https://arxiv.org/abs/2009.13658) 및 [Su et al.](https://arxiv.org/abs/2104.09864)의 연구에 따르면, 절대 위치 임베딩은 긴 텍스트 입력에 대해 대규모 언어 모델 성능이 저하됩니다. 긴 텍스트 입력의 경우, 모델이 절대 위치 대신 입력 토큰 간의 상대적 위치 거리를 학습하는 것이 유리합니다.
+ 2. 학습된 위치 임베딩을 사용할 때, 대규모 언어 모델은 고정된 입력 길이 \\( N \\)으로 학습되어야 하므로, 학습된 입력 길이보다 더 긴 입력 길이에 대해 추론하는 것이 어렵습니다.
+
+최근에는 위에서 언급한 문제를 해결할 수 있는 상대적 위치 임베딩이 더 인기를 끌고 있습니다. 특히 다음과 같은 방법들이 주목받고 있습니다:
+
+- [Rotary Position Embedding (RoPE)](https://arxiv.org/abs/2104.09864)
+- [ALiBi](https://arxiv.org/abs/2108.12409)
+
+*RoPE*와 *ALiBi*는 모두 셀프 어텐션 알고리즘 내에서 직접적으로 문장 순서를 모델에게 알려주는 것이 최선이라고 주장합니다. 이는 단어 토큰이 서로 관계를 맺는 곳이기 때문입니다. 구체적으로, 문장 순서를 \\( \mathbf{QK}^T \\) 계산을 수정하는 방식으로 알려주어야 한다는 것입니다.
+
+너무 많은 세부 사항을 다루지 않고, *RoPE*는 위치 정보를 쿼리-키 쌍에 인코딩할 수 있다고 지적합니다. 예를 들어, 각 벡터 \\( \mathbf{q}_i \\)와 \\( \mathbf{x}_j \\)를 각각 \\( \theta * i \\)와 \\( \theta * j \\)의 각도로 회전시킴으로써 다음과 같이 표현할 수 있습니다:
+
+$$ \mathbf{\hat{q}}_i^T \mathbf{\hat{x}}_j = \mathbf{{q}}_i^T \mathbf{R}_{\theta, i -j} \mathbf{{x}}_j. $$
+
+여기서 \\( \mathbf{R}_{\theta, i - j} \\)는 회전 행렬을 나타냅니다. \\( \theta \\)는 훈련 중에 *학습되지 않으며*, 대신 학습 중 최대 입력 시퀀스 길이에 따라 사전 정의된 값으로 설정됩니다.
+
+> 이렇게 함으로써 \\( \mathbf{q}_i \\)와 \\( \mathbf{q}_j \\) 간의 확률 점수는 \\( i \ne j \\)인 경우에만 영향을 받으며, 각 벡터의 특정 위치 \\( i \\)와 \\( j \\)와는 상관없이 오직 상대적 거리 \\( i - j \\)에만 의존하게 됩니다.
+
+*RoPE*는 현재 여러 중요한 대규모 언어 모델이 사용되고 있습니다. 예를 들면:
+
+- [**Falcon**](https://huggingface.co/tiiuae/falcon-40b)
+- [**Llama**](https://arxiv.org/abs/2302.13971)
+- [**PaLM**](https://arxiv.org/abs/2204.02311)
+
+대안으로, *ALiBi*는 훨씬 더 간단한 상대적 위치 인코딩 방식을 제안합니다. 입력 토큰 간의 상대적 거리를 음수인 정수로서 사전 정의된 값 `m`으로 스케일링하여 \\( \mathbf{QK}^T \\) 행렬의 각 쿼리-키 항목에 소프트맥스 계산 직전에 추가합니다.
+
+
+
+[ALiBi](https://arxiv.org/abs/2108.12409) 논문에서 보여주듯이, 이 간단한 상대적 위치 인코딩은 매우 긴 텍스트 입력 시퀀스에서도 모델이 높은 성능을 유지할 수 있게 합니다.
+
+*ALiBi*는 현재 여러 중요한 대규모 언어 모델 모델이 사용하고 있습니다. 예를 들면:
+
+- [**MPT**](https://huggingface.co/mosaicml/mpt-30b)
+- [**BLOOM**](https://huggingface.co/bigscience/bloom)
+
+*RoPE*와 *ALiBi* 위치 인코딩은 모두 학습 중에 보지 못한 입력 길이에 대해 확장할 수 있으며, *ALiBi*가 *RoPE*보다 더 잘 확장되는 것으로 나타났습니다. *ALiBi*의 경우, 하삼각 위치 행렬의 값을 입력 시퀀스 길이에 맞추어 증가시키기만 하면 됩니다. *RoPE*의 경우, 학습 중에 사용된 동일한 \\( \theta \\)를 유지하면 학습 중에 보지 못한 매우 긴 텍스트 입력을 전달할 때 성능이 저하됩니다(참고: [Press et al.](https://arxiv.org/abs/2108.12409)). 그러나 커뮤니티는 \\( \theta \\)를 조정하는 몇 가지 효과적인 트릭을 찾아냈으며, 이를 통해 *RoPE* 위치 임베딩이 확장된 텍스트 입력 시퀀스에서도 잘 작동할 수 있게 되었습니다(참고: [here](https://github.com/huggingface/transformers/pull/24653)).
+
+> RoPE와 ALiBi는 모두 훈련 중에 *학습되지 않는* 상대적 위치 임베딩으로 다음과 같은 직관에 기반합니다:
+ - 텍스트 입력에 대한 위치 단서는 셀프 어텐션 레이어의 \\( QK^T \\) 행렬에 직접 제공되어야 합니다.
+ - 대규모 언어 모델은 일정한 *상대적* 거리 위치 인코딩을 서로 학습하도록 유도되어야 합니다.
+ - 텍스트 입력 토큰 간의 거리가 멀어질수록, 그들의 쿼리-값 확률은 낮아져야 합니다. RoPE와 ALiBi는 서로 멀리 떨어진 토큰의 쿼리-키 확률을 낮춥니다. RoPE는 쿼리-키 벡터 간의 각도를 증가시켜 벡터 곱을 감소시키는 방식으로, ALiBi는 벡터 곱에 큰 음수를 추가하는 방식으로 이 작업을 수행합니다.
+
+결론적으로, 큰 텍스트 입력을 처리해야 하는 작업에 배포될 예정인 대규모 언어 모델은 RoPE와 ALiBi와 같은 상대적 위치 임베딩으로 훈련하는 것이 더 좋습니다. 또한 RoPE와 ALiBi를 사용하여 훈련된 대규모 언어 모델이 고정 길이 \\( N_1 = 2048 \\)에서만 훈련되었더라도 위치 임베딩을 외삽하여 \\( N_1 \\)보다 훨씬 큰 텍스트 입력 \\( N_2 = 8192 > N_1 \\)로 실습에서 사용할 수 있음을 유의하세요.
+
+### 3.2 키-값 캐시 [[32-the-key-value-cache]]
+
+대규모 언어 모델을 이용한 자기회귀 텍스트 생성은 입력 시퀀스를 반복적으로 넣고, 다음 토큰을 샘플링하며, 그 다음 토큰을 입력 시퀀스에 추가하고, 대규모 언어 모델이 생성을 완료했다는 토큰을 생성할 때까지 이를 계속 수행하는 방식으로 작동합니다.
+
+자기회귀 생성이 어떻게 작동하는지에 대한 시각적 설명을 보려면 [Transformer's Generate Text Tutorial](https://huggingface.co/docs/transformers/llm_tutorial#generate-text)을 참조하세요.
+
+자기회귀 생성이 실제로 어떻게 작동하는지 보여주는 간단한 코드 스니펫을 실행해 보겠습니다. 여기서는 `torch.argmax`를 통해 가장 가능성이 높은 다음 토큰을 가져올 것입니다.
+
+```python
+input_ids = tokenizer(prompt, return_tensors="pt")["input_ids"].to("cuda")
+
+for _ in range(5):
+ next_logits = model(input_ids)["logits"][:, -1:]
+ next_token_id = torch.argmax(next_logits,dim=-1)
+
+ input_ids = torch.cat([input_ids, next_token_id], dim=-1)
+ print("shape of input_ids", input_ids.shape)
+
+generated_text = tokenizer.batch_decode(input_ids[:, -5:])
+generated_text
+```
+
+**출력**:
+```
+shape of input_ids torch.Size([1, 21])
+shape of input_ids torch.Size([1, 22])
+shape of input_ids torch.Size([1, 23])
+shape of input_ids torch.Size([1, 24])
+shape of input_ids torch.Size([1, 25])
+[' Here is a Python function']
+```
+
+보시다시피 샘플링된 토큰에 의해 텍스트 입력 토큰을 매번 증가시킵니다.
+
+매우 예외적인 경우를 제외하고, 대규모 언어 모델은 [인과적인 언어 모델링 목표](https://huggingface.co/docs/transformers/tasks/language_modeling#causal-language-modeling)를 사용하여 학습되므로 어텐션 점수의 상삼각 행렬을 마스킹합니다. 이것이 위의 두 다이어그램에서 어텐션 점수가 비어 있는 이유입니다 (즉, 0 확률을 가짐). 인과 언어 모델링에 대한 빠른 요약은 [*Illustrated Self Attention 블로그*](https://jalammar.github.io/illustrated-gpt2/#part-2-illustrated-self-attention)를 참조할 수 있습니다.
+
+결과적으로, 토큰은 *절대* 이전 토큰에 의존하지 않습니다. 더 구체적으로는 \\( \mathbf{q}_i \\) 벡터가 \\( j > i \\)인 경우 어떤 키, 값 벡터 \\( \mathbf{k}_j, \mathbf{v}j \\)와도 연관되지 않습니다. 대신 \\( \mathbf{q}i \\)는 이전의 키-값 벡터 \\( \mathbf{k}{m < i}, \mathbf{v}{m < i} \text{ , for } m \in {0, \ldots i - 1} \\)에만 주의를 기울입니다. 불필요한 계산을 줄이기 위해 각 층의 키-값 벡터를 모든 이전 시간 단계에 대해 캐시할 수 있습니다.
+
+다음으로, 대규모 언어 모델이 각 포워드 패스마다 키-값 캐시를 검색하고 전달하여 이를 활용하도록 합니다.
+Transformers에서는 `forward` 호출에 `use_cache` 플래그를 전달하여 키-값 캐시를 검색한 다음 현재 토큰과 함께 전달할 수 있습니다.
+
+```python
+past_key_values = None # past_key_values 는 키-값 캐시를 의미
+generated_tokens = []
+next_token_id = tokenizer(prompt, return_tensors="pt")["input_ids"].to("cuda")
+
+for _ in range(5):
+ next_logits, past_key_values = model(next_token_id, past_key_values=past_key_values, use_cache=True).to_tuple()
+ next_logits = next_logits[:, -1:]
+ next_token_id = torch.argmax(next_logits, dim=-1)
+
+ print("shape of input_ids", next_token_id.shape)
+ print("length of key-value cache", len(past_key_values[0][0])) # past_key_values 형태: [num_layers, 0 for k, 1 for v, batch_size, length, hidden_dim]
+ generated_tokens.append(next_token_id.item())
+
+generated_text = tokenizer.batch_decode(generated_tokens)
+generated_text
+```
+
+**출력**:
+```
+shape of input_ids torch.Size([1, 1])
+length of key-value cache 20
+shape of input_ids torch.Size([1, 1])
+length of key-value cache 21
+shape of input_ids torch.Size([1, 1])
+length of key-value cache 22
+shape of input_ids torch.Size([1, 1])
+length of key-value cache 23
+shape of input_ids torch.Size([1, 1])
+length of key-value cache 24
+[' Here', ' is', ' a', ' Python', ' function']
+```
+
+키-값 캐시를 사용할 때, 텍스트 입력 토큰의 길이는 *증가하지 않고* 단일 입력 벡터로 유지되는 것을 볼 수 있습니다. 반면에 키-값 캐시의 길이는 각 디코딩 단계마다 하나씩 증가합니다.
+
+> 키-값 캐시를 사용하면 \\( \mathbf{QK}^T \\)가 본질적으로 \\( \mathbf{q}_c\mathbf{K}^T \\)로 줄어드는데, 여기서 \\( \mathbf{q}_c \\)는 현재 전달된 입력 토큰의 쿼리 프로젝션으로, *항상* 단일 벡터입니다.
+
+키-값 캐시를 사용하는 것에는 두 가지 장점이 있습니다:
+- 전체 \\( \mathbf{QK}^T \\) 행렬을 계산하는 것과 비교하여 계산 효율성이 크게 향상됩니다. 이는 추론 속도의 증가로 이어집니다.
+- 생성된 토큰 수에 따라 필요한 최대 메모리가 이차적으로 증가하지 않고, 선형적으로만 증가합니다.
+
+> 더 긴 입력 시퀀스에 대해 동일한 결과와 큰 속도 향상을 가져오기 때문에 키-값 캐시를 *항상* 사용해야 합니다. Transformers는 텍스트 파이프라인이나 [`generate` 메서드](https://huggingface.co/docs/transformers/main_classes/text_generation)를 사용할 때 기본적으로 키-값 캐시를 활성화합니다.
+
+
+
+참고로, 키-값 캐시를 사용할 것을 권장하지만, 이를 사용할 때 LLM 출력이 약간 다를 수 있습니다. 이것은 행렬 곱셈 커널 자체의 특성 때문입니다 -- 더 자세한 내용은 [여기](https://github.com/huggingface/transformers/issues/25420#issuecomment-1775317535)에서 읽어볼 수 있습니다.
+
+
+
+#### 3.2.1 멀티 라운드 대화 [[321-multi-round-conversation]]
+
+키-값 캐시는 여러 번의 자기회귀 디코딩이 필요한 채팅과 같은 애플리케이션에 특히 유용합니다. 예제를 살펴보겠습니다.
+
+```
+User: How many people live in France?
+Assistant: Roughly 75 million people live in France
+User: And how many are in Germany?
+Assistant: Germany has ca. 81 million inhabitants
+```
+
+이 채팅에서 대규모 언어 모델은 두 번의 자기회귀 디코딩을 실행합니다:
+ 1. 첫 번째로, 키-값 캐시는 비어 있고 입력 프롬프트는 `"User: How many people live in France?"`입니다. 모델은 자기회귀적으로 `"Roughly 75 million people live in France"`라는 텍스트를 생성하며 디코딩 단계마다 키-값 캐시를 증가시킵니다.
+ 2. 두 번째로, 입력 프롬프트는 `"User: How many people live in France? \n Assistant: Roughly 75 million people live in France \n User: And how many in Germany?"`입니다. 캐시 덕분에 첫 번째 두 문장에 대한 모든 키-값 벡터는 이미 계산되어 있습니다. 따라서 입력 프롬프트는 `"User: And how many in Germany?"`로만 구성됩니다. 줄어든 입력 프롬프트를 처리하는 동안 계산된 키-값 벡터가 첫 번째 디코딩의 키-값 캐시에 연결됩니다. 두 번째 어시스턴트의 답변인 `"Germany has ca. 81 million inhabitants"`는 `"User: How many people live in France? \n Assistant: Roughly 75 million people live in France \n User: And how many are in Germany?"`의 인코딩된 키-값 벡터로 구성된 키-값 캐시를 사용하여 자기회귀적으로 생성됩니다.
+
+여기서 두 가지를 주목해야 합니다:
+ 1. 대규모 언어 모델이 대화의 모든 이전 문맥을 이해할 수 있도록 모든 문맥을 유지하는 것이 채팅에 배포된 대규모 언어 모델에서는 매우 중요합니다. 예를 들어, 위의 예에서 대규모 언어 모델은 사용자가 `"And how many are in Germany"`라고 물을 때 인구를 언급하고 있음을 이해해야 합니다.
+ 2. 키-값 캐시는 채팅에서 매우 유용합니다. 이는 인코딩된 채팅 기록을 처음부터 다시 인코딩할 필요 없이 계속해서 확장할 수 있게 해주기 때문입니다(예: 인코더-디코더 아키텍처를 사용할 때와 같은 경우).
+
+`transformers`에서 `generate` 호출은 기본적으로 `use_cache=True`와 함께 `return_dict_in_generate=True`를 전달하면 `past_key_values`를 반환합니다. 이는 아직 `pipeline` 인터페이스를 통해서는 사용할 수 없습니다.
+
+```python
+# 일반적인 생성
+prompt = system_prompt + "Question: Please write a function in Python that transforms bytes to Giga bytes.\n\nAnswer: Here"
+model_inputs = tokenizer(prompt, return_tensors='pt')
+generation_output = model.generate(**model_inputs, max_new_tokens=60, return_dict_in_generate=True)
+decoded_output = tokenizer.batch_decode(generation_output.sequences)[0]
+
+# 리턴된 `past_key_values`를 파이프라인화하여 다음 대화 라운드를 가속화
+prompt = decoded_output + "\nQuestion: How can I modify the function above to return Mega bytes instead?\n\nAnswer: Here"
+model_inputs = tokenizer(prompt, return_tensors='pt')
+generation_output = model.generate(
+ **model_inputs,
+ past_key_values=generation_output.past_key_values,
+ max_new_tokens=60,
+ return_dict_in_generate=True
+)
+tokenizer.batch_decode(generation_output.sequences)[0][len(prompt):]
+```
+
+**출력**:
+```
+ is a modified version of the function that returns Mega bytes instead.
+
+def bytes_to_megabytes(bytes):
+ return bytes / 1024 / 1024
+
+Answer: The function takes a number of bytes as input and returns the number of
+```
+
+훌륭합니다. 어텐션 층의 동일한 키와 값을 다시 계산하는 데 추가 시간이 소요되지 않습니다! 그러나 한 가지 문제가 있습니다. \\( \mathbf{QK}^T \\) 행렬에 필요한 최대 메모리는 크게 줄어들지만, 긴 입력 시퀀스나 다회차 채팅의 경우 키-값 캐시를 메모리에 보관하는 것이 매우 메모리 집약적이 될 수 있습니다. 키-값 캐시는 모든 자기 어텐션 층과 모든 어텐션 헤드에 대해 이전 입력 벡터 \\( \mathbf{x}_i \text{, for } i \in {1, \ldots, c - 1} \\)의 키-값 벡터를 저장해야 한다는 점을 기억하세요.
+
+이전에 사용한 대규모 언어 모델 `bigcode/octocoder`에 대해 키-값 캐시에 저장해야 하는 부동 소수점 값의 수를 계산해 봅시다.
+부동 소수점 값의 수는 시퀀스 길이의 두 배의 어텐션 헤드 수, 어텐션 헤드 차원, 레이어 수를 곱한 값입니다.
+가상의 입력 시퀀스 길이 16000에서 대규모 언어 모델에 대해 이를 계산하면 다음과 같습니다.
+
+```python
+config = model.config
+2 * 16_000 * config.n_layer * config.n_head * config.n_embd // config.n_head
+```
+
+**출력**:
+```
+7864320000
+```
+
+대략 80억 개의 부동 소수점 값입니다! `float16` 정밀도로 80억 개의 부동 소수점 값을 저장하는 데는 약 15GB의 RAM이 필요하며, 이는 모델 가중치 자체의 절반 정도입니다.
+연구자들은 키-값 캐시를 저장하는 데 필요한 메모리 비용을 크게 줄일 수 있는 두 가지 방법을 제안했으며, 이는 다음 절에서 살펴보겠습니다.
+
+#### 3.2.2 멀티 쿼리 어텐션 (MQA) [[322-multi-query-attention-mqa]]
+
+[멀티 쿼리 어텐션 (MQA)](https://arxiv.org/abs/1911.02150)은 Noam Shazeer의 *Fast Transformer Decoding: One Write-Head is All You Need* 논문에서 제안되었습니다. 제목에서 알 수 있듯이, Noam은 `n_head` 키-값 프로젝션 가중치 대신, 모든 어텐션 헤드에서 공유되는 단일 헤드-값 프로젝션 가중치를 사용할 수 있으며, 이를 통해 모델 성능이 크게 저하되지 않는다는 것을 발견했습니다.
+
+> 단일 헤드-값 프로젝션 가중치를 사용함으로써, 키-값 벡터 \\( \mathbf{k}_i, \mathbf{v}_i \\)는 모든 어텐션 헤드에서 동일해야 하며, 이는 캐시에 `n_head` 개 대신 하나의 키-값 프로젝션 쌍만 저장하면 된다는 것을 의미합니다.
+
+대부분의 대규모 언어 모델이 20에서 100 사이의 어텐션 헤드를 사용하기 때문에, MQA는 키-값 캐시의 메모리 소비를 크게 줄입니다. 이 노트북에서 사용된 대규모 언어 모델의 경우, 입력 시퀀스 길이 16000에서 필요한 메모리 소비를 15GB에서 400MB 미만으로 줄일 수 있습니다.
+
+메모리 절감 외에도, MQA는 계산 효율성도 향상시킵니다. 다음과 같이 설명합니다.
+자기회귀 디코딩에서는 큰 키-값 벡터를 다시 로드하고, 현재 키-값 벡터 쌍과 연결한 후 \\( \mathbf{q}_c\mathbf{K}^T \\) 계산에 매 단계마다 입력해야 합니다. 자기회귀 디코딩의 경우, 지속적인 재로드에 필요한 메모리 대역폭이 심각한 시간 병목 현상을 가져올 수 있습니다. 키-값 벡터의 크기를 줄이면 접근해야 하는 메모리 양이 줄어들어 메모리 대역폭 병목 현상이 감소합니다. 자세한 내용은 [Noam의 논문](https://arxiv.org/abs/1911.02150)을 참조하세요.
+
+여기서 이해해야 할 중요한 부분은 키-값 어텐션 헤드 수를 1로 줄이는 것이 키-값 캐시를 사용할 때만 의미가 있다는 것입니다. 키-값 캐시 없이 단일 포워드 패스에 대한 모델의 최대 메모리 소비는 변경되지 않으며, 각 어텐션 헤드는 여전히 고유한 쿼리 벡터를 가지므로 각 어텐션 헤드는 여전히 다른 \\( \mathbf{QK}^T \\) 행렬을 가집니다.
+
+MQA는 커뮤니티에서 널리 채택되어 현재 가장 인기 있는 많은 대규모 언어 모델에서 사용되고 있습니다.
+
+- [**Falcon**](https://huggingface.co/tiiuae/falcon-40b)
+- [**PaLM**](https://arxiv.org/abs/2204.02311)
+- [**MPT**](https://huggingface.co/mosaicml/mpt-30b)
+- [**BLOOM**](https://huggingface.co/bigscience/bloom)
+
+또한, 이 노트북에서 사용된 체크포인트 `bigcode/octocoder`는 MQA를 사용합니다.
+
+#### 3.2.3 그룹 쿼리 어텐션 (GQA) [[323-grouped-query-attention-gqa]]
+
+[그룹 쿼리 어텐션 (GQA)](https://arxiv.org/abs/2305.13245)은 Google의 Ainslie 등의 연구진들에 의해 제안되었습니다. 그들은 MQA를 사용하는 것이 종종 일반적인 멀티 키-값 헤드 프로젝션을 사용하는 것보다 품질 저하를 가져올 수 있다는 것을 발견했습니다. 이 논문은 쿼리 헤드 프로젝션 가중치의 수를 너무 극단적으로 줄이는 대신, 더 많은 모델 성능을 유지할 수 있다고 주장합니다. 단일 키-값 프로젝션 가중치 대신, `n < n_head` 키-값 프로젝션 가중치를 사용해야 합니다. `n_head`보다 훨씬 작은 `n`값, 예를 들어 2, 4 또는 8을 선택하면, MQA의 거의 모든 메모리 및 속도 이점을 유지하면서 모델 용량을 덜 희생하고 따라서 성능 저하를 줄일 수 있습니다.
+
+또한, GQA의 저자들은 기존 모델 체크포인트를 원래 사전 학습 계산의 5% 정도의 적은 양으로 GQA 아키텍처로 *업트레이닝*할 수 있음을 발견했습니다. 원래 사전 학습 계산의 5%가 여전히 엄청난 양일 수 있지만, GQA *업트레이닝*은 기존 체크포인트가 더 긴 입력 시퀀스에서도 유용하도록 합니다.
+
+GQA는 최근에 제안되었기 때문에 이 노트북을 작성할 당시에는 채택이 덜 되었습니다.
+GQA의 가장 주목할 만한 적용 사례는 [Llama-v2](https://huggingface.co/meta-llama/Llama-2-70b-hf)입니다.
+
+> 결론적으로, 대규모 언어 모델이 자기회귀 디코딩으로 배포되면서 채팅과 같이 큰 입력 시퀀스를 가진 작업을 처리해야 하는 경우 GQA 또는 MQA를 사용하는 것이 강력히 권장됩니다.
+
+
+## 결론 [[conclusion]]
+
+연구 커뮤니티는 점점 더 큰 대규모 언어 모델의 추론 시간을 가속화하기 위한 새로운 기발한 방법들을 끊임없이 찾아내고 있습니다. 예를 들어, [추측 디코딩](https://arxiv.org/abs/2211.17192)이라는 유망한 연구 방향이 있습니다. 여기서 "쉬운 토큰"은 더 작고 빠른 언어 모델에 의해 생성되고, "어려운 토큰"만 대규모 언어 모델 자체에 의해 생성됩니다. 자세한 내용은 이 노트북의 범위를 벗어나지만, [멋진 블로그 포스트](https://huggingface.co/blog/assisted-generation)에서 읽어볼 수 있습니다.
+
+GPT3/4, Llama-2-70b, Claude, PaLM과 같은 거대한 대규모 언어 모델이 [Hugging Face Chat](https://huggingface.co/chat/) 또는 ChatGPT와 같은 채팅 인터페이스에서 빠르게 실행될 수 있는 이유는 위에서 언급한 정밀도, 알고리즘, 아키텍처의 개선 덕분입니다. 앞으로 GPU, TPU 등과 같은 가속기는 점점 더 빨라지고 더 많은 메모리를 사용할 것입니다. 따라서 가장 좋은 알고리즘과 아키텍처를 사용하여 최고의 효율을 얻는 것이 중요합니다 🤗
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/agent.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/agent.md
new file mode 100644
index 0000000000000000000000000000000000000000..d0ef630e2cdf77f4d5755acdc06666c1bd78e88d
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/agent.md
@@ -0,0 +1,134 @@
+
+
+# 에이전트 & 도구 [[agents-tools]]
+
+
+
+Transformers Agent는 실험 중인 API이므로 언제든지 변경될 수 있습니다.
+API나 기반 모델이 자주 업데이트되므로, 에이전트가 제공하는 결과물은 달라질 수 있습니다.
+
+
+
+에이전트와 도구에 대해 더 알아보려면 [소개 가이드](../transformers_agents)를 꼭 읽어보세요.
+이 페이지에는 기본 클래스에 대한 API 문서가 포함되어 있습니다.
+
+## 에이전트 [[agents]]
+
+우리는 기본 [`Agent`] 클래스를 기반으로 두 가지 유형의 에이전트를 제공합니다:
+- [`CodeAgent`]는 한 번에 동작합니다. 작업을 해결하기 위해 코드를 생성한 다음, 바로 실행합니다.
+- [`ReactAgent`]는 단계별로 동작하며, 각 단계는 하나의 생각, 하나의 도구 호출 및 실행으로 구성됩니다. 이 에이전트에는 두 가지 클래스가 있습니다:
+ - [`ReactJsonAgent`]는 도구 호출을 JSON으로 작성합니다.
+ - [`ReactCodeAgent`]는 도구 호출을 Python 코드로 작성합니다.
+
+### Agent [[agent]]
+
+[[autodoc]] Agent
+
+### CodeAgent [[codeagent]]
+
+[[autodoc]] CodeAgent
+
+### React agents [[react-agents]]
+
+[[autodoc]] ReactAgent
+
+[[autodoc]] ReactJsonAgent
+
+[[autodoc]] ReactCodeAgent
+
+## Tools [[tools]]
+
+### load_tool [[loadtool]]
+
+[[autodoc]] load_tool
+
+### Tool [[tool]]
+
+[[autodoc]] Tool
+
+### Toolbox [[toolbox]]
+
+[[autodoc]] Toolbox
+
+### PipelineTool [[pipelinetool]]
+
+[[autodoc]] PipelineTool
+
+### launch_gradio_demo [[launchgradiodemo]]
+
+[[autodoc]] launch_gradio_demo
+
+### ToolCollection [[toolcollection]]
+
+[[autodoc]] ToolCollection
+
+## 엔진 [[engines]]
+
+에이전트 프레임워크에서 사용할 수 있는 엔진을 자유롭게 만들고 사용할 수 있습니다.
+이 엔진들은 다음과 같은 사양을 가지고 있습니다:
+1. 입력(`List[Dict[str, str]]`)에 대한 [메시지 형식](../chat_templating.md)을 따르고 문자열을 반환해야 합니다.
+2. 인수 `stop_sequences`에 시퀀스가 전달되기 *전에* 출력을 생성하는 것을 중지해야 합니다.
+
+### HfApiEngine [[HfApiEngine]]
+
+편의를 위해, 위의 사항을 구현하고 대규모 언어 모델 실행을 위해 추론 엔드포인트를 사용하는 `HfApiEngine`을 추가했습니다.
+
+```python
+>>> from transformers import HfApiEngine
+
+>>> messages = [
+... {"role": "user", "content": "Hello, how are you?"},
+... {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+... {"role": "user", "content": "No need to help, take it easy."},
+... ]
+
+>>> HfApiEngine()(messages, stop_sequences=["conversation"])
+
+"That's very kind of you to say! It's always nice to have a relaxed "
+```
+
+[[autodoc]] HfApiEngine
+
+
+## 에이전트 유형 [[agent-types]]
+
+에이전트는 도구 간의 모든 유형의 객체를 처리할 수 있습니다; 도구는 완전히 멀티모달이므로 텍스트, 이미지, 오디오, 비디오 등 다양한 유형을 수락하고 반환할 수 있습니다.
+도구 간의 호환성을 높이고 ipython (jupyter, colab, ipython 노트북, ...)에서 이러한
+반환 값을 올바르게 렌더링하기 위해 이러한 유형을 중심으로 래퍼 클래스를
+구현합니다.
+
+래핑된 객체는 처음과 동일하게 작동해야 합니다; 텍스트 객체는 여전히 문자열로 작동해야 하며,
+이미지 객체는 여전히 `PIL.Image`로 작동해야 합니다.
+
+이러한 유형에는 세 가지 특정 목적이 있습니다:
+
+- `to_raw`를 호출하면 기본 객체가 반환되어야 합니다.
+- `to_string`을 호출하면 객체가 문자열로 반환되어야 합니다:
+`AgentText`의 경우 문자열이 될 수 있지만, 다른 경우에는 객체의 직렬화된 버전의 경로일 수 있습니다.
+- ipython 커널에서 표시할 때 객체가 올바르게 표시되어야 합니다.
+
+### AgentText [[agenttext]]
+
+[[autodoc]] transformers.agents.agent_types.AgentText
+
+### AgentImage [[agentimage]]
+
+[[autodoc]] transformers.agents.agent_types.AgentImage
+
+### AgentAudio [[agentaudio]]
+
+[[autodoc]] transformers.agents.agent_types.AgentAudio
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/callback.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/callback.md
new file mode 100644
index 0000000000000000000000000000000000000000..1f280a412989e756b3882f10c9383233e60c08d0
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/callback.md
@@ -0,0 +1,133 @@
+
+
+# 콜백 [[callbacks]]
+
+콜백은 PyTorch [`Trainer`]의 반복 학습 동작을 사용자 정의할 수 있는 객체입니다
+(이 기능은 TensorFlow에서는 아직 구현되지 않았습니다). 콜백은 반복 학습의 상태를
+검사하여 (진행 상황 보고, TensorBoard 또는 기타 머신 러닝 플랫폼에 로그 남기기 등)
+결정(예: 조기 종료)을 내릴 수 있습니다.
+
+콜백은 [`TrainerControl`] 객체를 반환하는 것 외에는 반복 학습에서 어떤 것도 변경할 수 없는
+"읽기 전용" 코드 조각입니다. 반복 학습에 변경이 필요한 사용자 정의 작업이 필요한 경우,
+[`Trainer`]를 서브클래스로 만들어 필요한 메소드들을 오버라이드해야 합니다 (예시는 [trainer](trainer)를 참조하세요).
+
+기본적으로 `TrainingArguments.report_to`는 `"all"`로 설정되어 있으므로, [`Trainer`]는 다음 콜백을 사용합니다.
+
+- [`DefaultFlowCallback`]는 로그, 저장, 평가에 대한 기본 동작을 처리합니다.
+- [`PrinterCallback`] 또는 [`ProgressCallback`]는 진행 상황을 표시하고 로그를 출력합니다
+ ([`TrainingArguments`]를 통해 tqdm을 비활성화하면 첫 번째 콜백이 사용되고, 그렇지 않으면 두 번째가 사용됩니다).
+- [`~integrations.TensorBoardCallback`]는 TensorBoard가 (PyTorch >= 1.4
+ 또는 tensorboardX를 통해) 접근 가능하면 사용됩니다.
+- [`~integrations.WandbCallback`]는 [wandb](https://www.wandb.com/)가 설치되어 있으면
+ 사용됩니다.
+- [`~integrations.CometCallback`]는 [comet_ml](https://www.comet.com/site/)이 설치되어 있으면 사용됩니다.
+- [`~integrations.MLflowCallback`]는 [mlflow](https://www.mlflow.org/)가 설치되어 있으면 사용됩니다.
+- [`~integrations.NeptuneCallback`]는 [neptune](https://neptune.ai/)이 설치되어 있으면 사용됩니다.
+- [`~integrations.AzureMLCallback`]는 [azureml-sdk](https://pypi.org/project/azureml-sdk/)가 설치되어
+ 있으면 사용됩니다.
+- [`~integrations.CodeCarbonCallback`]는 [codecarbon](https://pypi.org/project/codecarbon/)이 설치되어
+ 있으면 사용됩니다.
+- [`~integrations.ClearMLCallback`]는 [clearml](https://github.com/allegroai/clearml)이 설치되어 있으면 사용됩니다.
+- [`~integrations.DagsHubCallback`]는 [dagshub](https://dagshub.com/)이 설치되어 있으면 사용됩니다.
+- [`~integrations.FlyteCallback`]는 [flyte](https://flyte.org/)가 설치되어 있으면 사용됩니다.
+- [`~integrations.DVCLiveCallback`]는 [dvclive](https://dvc.org/doc/dvclive)가 설치되어 있으면 사용됩니다.
+
+패키지가 설치되어 있지만 해당 통합 기능을 사용하고 싶지 않다면, `TrainingArguments.report_to`를 사용하고자 하는 통합 기능 목록으로 변경할 수 있습니다 (예: `["azure_ml", "wandb"]`).
+
+콜백을 구현하는 주요 클래스는 [`TrainerCallback`]입니다. 이 클래스는 [`Trainer`]를
+인스턴스화하는 데 사용된 [`TrainingArguments`]를 가져오고, 해당 Trainer의 내부 상태를
+[`TrainerState`]를 통해 접근할 수 있으며, [`TrainerControl`]을 통해 반복 학습에서 일부
+작업을 수행할 수 있습니다.
+
+
+## 사용 가능한 콜백 [[available-callbacks]]
+
+라이브러리에서 사용 가능한 [`TrainerCallback`] 목록은 다음과 같습니다:
+
+[[autodoc]] integrations.CometCallback
+ - setup
+
+[[autodoc]] DefaultFlowCallback
+
+[[autodoc]] PrinterCallback
+
+[[autodoc]] ProgressCallback
+
+[[autodoc]] EarlyStoppingCallback
+
+[[autodoc]] integrations.TensorBoardCallback
+
+[[autodoc]] integrations.WandbCallback
+ - setup
+
+[[autodoc]] integrations.MLflowCallback
+ - setup
+
+[[autodoc]] integrations.AzureMLCallback
+
+[[autodoc]] integrations.CodeCarbonCallback
+
+[[autodoc]] integrations.NeptuneCallback
+
+[[autodoc]] integrations.ClearMLCallback
+
+[[autodoc]] integrations.DagsHubCallback
+
+[[autodoc]] integrations.FlyteCallback
+
+[[autodoc]] integrations.DVCLiveCallback
+ - setup
+
+## TrainerCallback [[trainercallback]]
+
+[[autodoc]] TrainerCallback
+
+여기 PyTorch [`Trainer`]와 함께 사용자 정의 콜백을 등록하는 예시가 있습니다:
+
+```python
+class MyCallback(TrainerCallback):
+ "A callback that prints a message at the beginning of training"
+
+ def on_train_begin(self, args, state, control, **kwargs):
+ print("Starting training")
+
+
+trainer = Trainer(
+ model,
+ args,
+ train_dataset=train_dataset,
+ eval_dataset=eval_dataset,
+ callbacks=[MyCallback], # 우리는 콜백 클래스를 이 방식으로 전달하거나 그것의 인스턴스(MyCallback())를 전달할 수 있습니다
+)
+```
+
+또 다른 콜백을 등록하는 방법은 `trainer.add_callback()`을 호출하는 것입니다:
+
+```python
+trainer = Trainer(...)
+trainer.add_callback(MyCallback)
+# 다른 방법으로는 콜백 클래스의 인스턴스를 전달할 수 있습니다
+trainer.add_callback(MyCallback())
+```
+
+## TrainerState [[trainerstate]]
+
+[[autodoc]] TrainerState
+
+## TrainerControl [[trainercontrol]]
+
+[[autodoc]] TrainerControl
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/configuration.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/configuration.md
new file mode 100644
index 0000000000000000000000000000000000000000..6c6278a02585608a66a600cd610c81af995aaebf
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/configuration.md
@@ -0,0 +1,28 @@
+
+
+# 구성[[configuration]]
+
+기본 클래스 [`PretrainedConfig`]는 로컬 파일이나 디렉토리, 또는 라이브러리에서 제공하는 사전 학습된 모델 구성(HuggingFace의 AWS S3 저장소에서 다운로드됨)으로부터 구성을 불러오거나 저장하는 공통 메서드를 구현합니다. 각 파생 구성 클래스는 모델별 특성을 구현합니다.
+
+모든 구성 클래스에 존재하는 공통 속성은 다음과 같습니다: `hidden_size`, `num_attention_heads`, `num_hidden_layers`. 텍스트 모델은 추가로 `vocab_size`를 구현합니다.
+
+
+## PretrainedConfig[[transformers.PretrainedConfig]]
+
+[[autodoc]] PretrainedConfig
+ - push_to_hub
+ - all
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/data_collator.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/data_collator.md
new file mode 100644
index 0000000000000000000000000000000000000000..0e677c7d8979b87b418d800978174f1a65701f3a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/data_collator.md
@@ -0,0 +1,66 @@
+
+
+# 데이터 콜레이터(Data Collator)[[data-collator]]
+
+데이터 콜레이터는 데이터셋 요소들의 리스트를 입력으로 사용하여 배치를 형성하는 객체입니다. 이러한 요소들은 `train_dataset` 또는 `eval_dataset의` 요소들과 동일한 타입 입니다. 배치를 구성하기 위해, 데이터 콜레이터는 (패딩과 같은) 일부 처리를 적용할 수 있습니다. [`DataCollatorForLanguageModeling`]과 같은 일부 콜레이터는 형성된 배치에 (무작위 마스킹과 같은) 일부 무작위 데이터 증강도 적용합니다. 사용 예시는 [예제 스크립트](../examples)나 [예제 노트북](../notebooks)에서 찾을 수 있습니다.
+
+
+## 기본 데이터 콜레이터[[transformers.default_data_collator]]
+
+[[autodoc]] data.data_collator.default_data_collator
+
+## DefaultDataCollator[[transformers.DefaultDataCollator]]
+
+[[autodoc]] data.data_collator.DefaultDataCollator
+
+## DataCollatorWithPadding[[transformers.DataCollatorWithPadding]]
+
+[[autodoc]] data.data_collator.DataCollatorWithPadding
+
+## DataCollatorForTokenClassification[[transformers.DataCollatorForTokenClassification]]
+
+[[autodoc]] data.data_collator.DataCollatorForTokenClassification
+
+## DataCollatorForSeq2Seq[[transformers.DataCollatorForSeq2Seq]]
+
+[[autodoc]] data.data_collator.DataCollatorForSeq2Seq
+
+## DataCollatorForLanguageModeling[[transformers.DataCollatorForLanguageModeling]]
+
+[[autodoc]] data.data_collator.DataCollatorForLanguageModeling
+ - numpy_mask_tokens
+ - tf_mask_tokens
+ - torch_mask_tokens
+
+## DataCollatorForWholeWordMask[[transformers.DataCollatorForWholeWordMask]]
+
+[[autodoc]] data.data_collator.DataCollatorForWholeWordMask
+ - numpy_mask_tokens
+ - tf_mask_tokens
+ - torch_mask_tokens
+
+## DataCollatorForPermutationLanguageModeling[[transformers.DataCollatorForPermutationLanguageModeling]]
+
+[[autodoc]] data.data_collator.DataCollatorForPermutationLanguageModeling
+ - numpy_mask_tokens
+ - tf_mask_tokens
+ - torch_mask_tokens
+
+## DataCollatorWithFlatteningtransformers.DataCollatorWithFlattening
+
+[[autodoc]] data.data_collator.DataCollatorWithFlattening
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/executorch.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/executorch.md
new file mode 100644
index 0000000000000000000000000000000000000000..a94418ece1a7abcc88b46afea148d02e89683c61
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/executorch.md
@@ -0,0 +1,33 @@
+
+
+
+# ExecuTorch [[executorch]]
+
+[`ExecuTorch`](https://github.com/pytorch/executorch) 는 웨어러블, 임베디드 장치, 마이크로컨트롤러를 포함한 모바일 및 엣지 장치에서 온디바이스 추론 기능을 가능하게 하는 종합 솔루션입니다. PyTorch 생태계에 속해있으며, 이식성, 생산성, 성능에 중점을 둔 PyTorch 모델 배포를 지원합니다.
+
+ExecuTorch는 백엔드 위임, 사용자 정의 컴파일러 변환, 메모리 계획 등 모델, 장치 또는 특정 유즈케이스 맞춤 최적화를 수행할 수 있는 진입점을 명확하게 정의합니다. ExecuTorch를 사용해 엣지 장치에서 PyTorch 모델을 실행하는 첫 번째 단계는 모델을 익스포트하는 것입니다. 이 작업은 PyTorch API인 [`torch.export`](https://pytorch.org/docs/stable/export.html)를 사용하여 수행합니다.
+
+
+## ExecuTorch 통합 [[transformers.TorchExportableModuleWithStaticCache]]
+
+`torch.export`를 사용하여 🤗 Transformers를 익스포트 할 수 있도록 통합 지점이 개발되고 있습니다. 이 통합의 목표는 익스포트뿐만 아니라, 익스포트한 아티팩트가 `ExecuTorch`에서 효율적으로 실행될 수 있도록 더 축소하고 최적화하는 것입니다. 특히 모바일 및 엣지 유즈케이스에 중점을 두고 있습니다.
+
+[[autodoc]] integrations.executorch.TorchExportableModuleWithStaticCache
+ - forward
+
+[[autodoc]] integrations.executorch.convert_and_export_with_cache
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/feature_extractor.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/feature_extractor.md
new file mode 100644
index 0000000000000000000000000000000000000000..7c667424c4ff956a1b1dce95db970b88d5aa7eb4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/feature_extractor.md
@@ -0,0 +1,39 @@
+
+
+# 특성 추출기 [[feature-extractor]]
+
+특성 추출기는 오디오 또는 비전 모델을 위한 입력 특성을 준비하는 역할을 합니다. 여기에는 시퀀스에서 특성을 추출하는 작업(예를 들어, 오디오 파일을 전처리하여 Log-Mel 스펙트로그램 특성을 생성하는 것), 이미지에서 특성을 추출하는 작업(예를 들어, 이미지 파일을 자르는 것)이 포함됩니다. 뿐만 아니라 패딩, 정규화 및 NumPy, PyTorch, TensorFlow 텐서로의 변환도 포함됩니다.
+
+
+## FeatureExtractionMixin [[transformers.FeatureExtractionMixin]]
+
+[[autodoc]] feature_extraction_utils.FeatureExtractionMixin
+ - from_pretrained
+ - save_pretrained
+
+## SequenceFeatureExtractor [[transformers.SequenceFeatureExtractor]]
+
+[[autodoc]] SequenceFeatureExtractor
+ - pad
+
+## BatchFeature [[transformers.BatchFeature]]
+
+[[autodoc]] BatchFeature
+
+## ImageFeatureExtractionMixin [[transformers.ImageFeatureExtractionMixin]]
+
+[[autodoc]] image_utils.ImageFeatureExtractionMixin
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/keras_callbacks.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/keras_callbacks.md
new file mode 100644
index 0000000000000000000000000000000000000000..25d5ea3e40083acad8fa9257ce2c7cfef7c3d9c8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/keras_callbacks.md
@@ -0,0 +1,27 @@
+
+
+# 케라스 콜백[[keras-callbacks]]
+
+케라스로 트랜스포머 모델을 학습할 때, 일반적인 작업을 자동화하기 위한 라이브러리 전용 콜백들을 사용 할 수 있습니다.
+
+## KerasMetricCallback[[transformers.KerasMetricCallback]]
+
+[[autodoc]] KerasMetricCallback
+
+## PushToHubCallback[[transformers.PushToHubCallback]]
+
+[[autodoc]] PushToHubCallback
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/logging.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/logging.md
new file mode 100644
index 0000000000000000000000000000000000000000..55e1a21c7bd57bb1b9f8e0f47052fa085340f65b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/logging.md
@@ -0,0 +1,108 @@
+
+
+# 로깅 [[logging]]
+
+🤗 트랜스포머는 중앙 집중식 로깅 시스템을 제공하여 라이브러리의 출력 레벨을 쉽게 설정할 수 있습니다.
+
+현재 라이브러리의 기본 출력 레벨은 `WARNING`으로 설정되어 있습니다.
+
+출력 레벨을 변경하려면 직접적인 설정 메서드를 사용할 수 있습니다. 예를 들어, 출력 레벨을 INFO 수준으로 변경하는 방법은 다음과 같습니다.
+
+```python
+import transformers
+
+transformers.logging.set_verbosity_info()
+```
+
+환경 변수 `TRANSFORMERS_VERBOSITY`를 사용하여 기본 출력 레벨을 재정의할 수도 있습니다. 이를 `debug`, `info`, `warning`, `error`, `critical`, `fatal` 중 하나로 설정할 수 있습니다. 예를 들어 다음과 같습니다.
+
+```bash
+TRANSFORMERS_VERBOSITY=error ./myprogram.py
+```
+
+또한, 일부 `warnings`는 환경 변수 `TRANSFORMERS_NO_ADVISORY_WARNINGS`를 1과 같은 true 값으로 설정하여 비활성화할 수 있습니다. 이렇게 하면 [`logger.warning_advice`]를 사용하여 기록된 경고가 비활성화됩니다. 예를 들어 다음과 같습니다.
+
+```bash
+TRANSFORMERS_NO_ADVISORY_WARNINGS=1 ./myprogram.py
+```
+
+다음은 라이브러리와 동일한 로거를 자신의 모듈이나 스크립트에서 사용하는 방법에 대한 예시입니다.
+
+```python
+from transformers.utils import logging
+
+logging.set_verbosity_info()
+logger = logging.get_logger("transformers")
+logger.info("INFO")
+logger.warning("WARN")
+```
+
+
+이 로깅 모듈의 모든 메서드는 아래에 문서화되어 있으며, 주요 메서드는 현재 로거의 출력 수준을 가져오는 [`logging.get_verbosity`]와 원하는 출력 수준으로 설정하는 [`logging.set_verbosity`] 입니다. 출력 수준은 (가장 적은 출력에서 가장 많은 출력 순으로) 다음과 같으며, 해당 수준에 대응하는 정수 값은 괄호 안에 표시됩니다.
+
+- `transformers.logging.CRITICAL` 또는 `transformers.logging.FATAL` (정숫값, 50): 가장 심각한 오류만 보고합니다.
+- `transformers.logging.ERROR` (정숫값, 40): 오류만 보고합니다.
+- `transformers.logging.WARNING` 또는 `transformers.logging.WARN` (정숫값, 30): 오류와 경고만 보고합니다. 이는 라이브러리에서 기본으로 사용되는 수준입니다.
+- `transformers.logging.INFO` (정숫값, 20): 오류, 경고, 그리고 기본적인 정보를 보고합니다.
+- `transformers.logging.DEBUG` (정숫값, 10): 모든 정보를 보고합니다.
+
+기본적으로 모델 다운로드 중에는 `tqdm` 진행 표시줄이 표시됩니다. [`logging.disable_progress_bar`]와 [`logging.enable_progress_bar`]를 사용하여 이 동작을 숨기거나 다시 표시할 수 있습니다.
+
+## `logging` vs `warnings`[[transformers.utils.logging.captureWarnings]]
+
+Python에는 종종 함께 사용되는 두 가지 로깅 시스템이 있습니다. 위에서 설명한 `logging`과 `warnings`입니다. `warnings`는 특정 범주로 경고를 세분화할 수 있습니다. 예를 들어, 이미 더 이상 사용되지 않는 기능이나 경로에 대해 `FutureWarning`이 사용되고, 곧 사용 중단될 기능을 알리기 위해 `DeprecationWarning`이 사용됩니다.
+
+트랜스포머 라이브러리에서는 두 시스템 모두를 사용합니다. `logging`의 `captureWarnings` 메서드를 활용하고 이를 조정하여 위에서 설명한 출력 수준 설정자들을 통해 이러한 경고 메시지들을 관리할 수 있도록 합니다.
+
+라이브러리 개발자는 다음과 같은 지침을 따르는 것이 좋습니다.
+
+- `warnings`는 라이브러리 개발자와 `transformers`에 의존하는 라이브러리 개발자들에게 유리합니다.
+- `logging`은 일반적인 프로젝트 라이브러리 개발자보다는, 라이브러리를 사용하는 최종 사용자들에게 유리할 것입니다.
+
+아래에서 `captureWarnings` 메소드에 대한 참고 사항을 확인할 수 있습니다.
+
+[[autodoc]] logging.captureWarnings
+
+## 기본 설정자 [[transformers.utils.logging.set_verbosity_error]]
+
+[[autodoc]] logging.set_verbosity_error
+
+[[autodoc]] logging.set_verbosity_warning
+
+[[autodoc]] logging.set_verbosity_info
+
+[[autodoc]] logging.set_verbosity_debug
+
+## 기타 함수 [[transformers.utils.logging.get_verbosity]]
+
+[[autodoc]] logging.get_verbosity
+
+[[autodoc]] logging.set_verbosity
+
+[[autodoc]] logging.get_logger
+
+[[autodoc]] logging.enable_default_handler
+
+[[autodoc]] logging.disable_default_handler
+
+[[autodoc]] logging.enable_explicit_format
+
+[[autodoc]] logging.reset_format
+
+[[autodoc]] logging.enable_progress_bar
+
+[[autodoc]] logging.disable_progress_bar
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/model.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/model.md
new file mode 100644
index 0000000000000000000000000000000000000000..71a9768deee1ecf1badbbe60fe0152eb1756cde6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/model.md
@@ -0,0 +1,68 @@
+
+
+# 모델
+
+기본 클래스 [`PreTrainedModel`], [`TFPreTrainedModel`], [`FlaxPreTrainedModel`]는 로컬 파일과 디렉토리로부터 모델을 로드하고 저장하거나 또는 (허깅페이스 AWS S3 리포지토리로부터 다운로드된) 라이브러리에서 제공하는 사전 훈련된 모델 설정을 로드하고 저장하는 것을 지원하는 기본 메소드를 구현하였습니다.
+
+[`PreTrainedModel`]과 [`TFPreTrainedModel`]은 또한 모든 모델들을 공통적으로 지원하는 메소드 여러개를 구현하였습니다:
+
+- 새 토큰이 단어장에 추가될 때, 입력 토큰 임베딩의 크기를 조정합니다.
+- 모델의 어텐션 헤드를 가지치기합니다.
+
+각 모델에 공통인 다른 메소드들은 다음의 클래스에서 정의됩니다.
+- [`~modeling_utils.ModuleUtilsMixin`](파이토치 모델용)
+- 텍스트 생성을 위한 [`~modeling_tf_utils.TFModuleUtilsMixin`](텐서플로 모델용)
+- [`~generation.GenerationMixin`](파이토치 모델용)
+- [`~generation.FlaxGenerationMixin`](Flax/JAX 모델용)
+
+## PreTrainedModel
+
+[[autodoc]] PreTrainedModel
+ - push_to_hub
+ - all
+
+사용자 정의 모델은 초고속 초기화(superfast init)가 특정 모델에 적용될 수 있는지 여부를 결정하는 `_supports_assign_param_buffer`도 포함해야 합니다.
+`test_save_and_load_from_pretrained` 실패 시, 모델이 `_supports_assign_param_buffer`를 필요로 하는지 확인하세요.
+필요로 한다면 `False`로 설정하세요.
+
+## ModuleUtilsMixin
+
+[[autodoc]] modeling_utils.ModuleUtilsMixin
+
+## TFPreTrainedModel
+
+[[autodoc]] TFPreTrainedModel
+ - push_to_hub
+ - all
+
+## TFModelUtilsMixin
+
+[[autodoc]] modeling_tf_utils.TFModelUtilsMixin
+
+## FlaxPreTrainedModel
+
+[[autodoc]] FlaxPreTrainedModel
+ - push_to_hub
+ - all
+
+## 허브에 저장하기
+
+[[autodoc]] utils.PushToHubMixin
+
+## 공유된 체크포인트
+
+[[autodoc]] modeling_utils.load_sharded_checkpoint
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/onnx.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/onnx.md
new file mode 100644
index 0000000000000000000000000000000000000000..510dab9df2f9332ca5a69252bd7c444e44bdf2e9
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/onnx.md
@@ -0,0 +1,50 @@
+
+
+# 🤗 Transformers 모델을 ONNX로 내보내기[[exporting--transformers-models-to-onnx]]
+
+🤗 트랜스포머는 `transformers.onnx` 패키지를 제공하며, 이 패키지는 설정 객체를 활용하여 모델 체크포인트를 ONNX 그래프로 변환할 수 있게 합니다.
+
+🤗 Transformers에 대한 자세한 내용은 [이 가이드](../serialization)를 참조하세요.
+
+## ONNX 설정[[onnx-configurations]]
+
+내보내려는(export) 모델 아키텍처의 유형에 따라 상속받아야 할 세 가지 추상 클래스를 제공합니다:
+
+* 인코더 기반 모델은 [`~onnx.config.OnnxConfig`]을 상속받습니다.
+* 디코더 기반 모델은 [`~onnx.config.OnnxConfigWithPast`]을 상속받습니다.
+* 인코더-디코더 기반 모델은 [`~onnx.config.OnnxSeq2SeqConfigWithPast`]을 상속받습니다.
+
+### OnnxConfig[[transformers.onnx.OnnxConfig]]
+
+[[autodoc]] onnx.config.OnnxConfig
+
+### OnnxConfigWithPast[[transformers.onnx.OnnxConfigWithPast]]
+
+[[autodoc]] onnx.config.OnnxConfigWithPast
+
+### OnnxSeq2SeqConfigWithPast[[OnnxSeq2SeqConfigWithPast]]
+
+[[autodoc]] onnx.config.OnnxSeq2SeqConfigWithPast
+
+## ONNX 특징[[onnx-features]]
+
+각 ONNX 설정은 다양한 유형의 토폴로지나 작업에 대해 모델을 내보낼 수 있게(exporting) 해주는 _features_ 세트와 연관되어 있습니다.
+
+### FeaturesManager[[transformers.onnx.FeaturesManager]]
+
+[[autodoc]] onnx.features.FeaturesManager
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/output.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/output.md
new file mode 100644
index 0000000000000000000000000000000000000000..e65a2c2c35906eef6cc4011994d4bdd50d9d3d76
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/output.md
@@ -0,0 +1,314 @@
+
+
+# 모델 출력[[model-outputs]]
+
+모든 모델에는 [`~utils.ModelOutput`]의 서브클래스의 인스턴스인 모델 출력이 있습니다. 이들은
+모델에서 반환되는 모든 정보를 포함하는 데이터 구조이지만 튜플이나 딕셔너리로도 사용할 수 있습니다.
+
+예제를 통해 살펴보겠습니다:
+
+```python
+from transformers import BertTokenizer, BertForSequenceClassification
+import torch
+
+tokenizer = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+model = BertForSequenceClassification.from_pretrained("google-bert/bert-base-uncased")
+
+inputs = tokenizer("Hello, my dog is cute", return_tensors="pt")
+labels = torch.tensor([1]).unsqueeze(0) # 배치 크기 1
+outputs = model(**inputs, labels=labels)
+```
+
+`outputs` 객체는 [`~modeling_outputs.SequenceClassifierOutput`]입니다.
+아래 해당 클래스의 문서에서 볼 수 있듯이, `loss`(선택적), `logits`, `hidden_states`(선택적) 및 `attentions`(선택적) 항목이 있습니다. 여기에서는 `labels`를 전달했기 때문에 `loss`가 있지만 `hidden_states`와 `attentions`가 없는데, 이는 `output_hidden_states=True` 또는 `output_attentions=True`를 전달하지 않았기 때문입니다.
+
+
+
+`output_hidden_states=True`를 전달할 때 `outputs.hidden_states[-1]`가 `outputs.last_hidden_state`와 정확히 일치할 것으로 예상할 수 있습니다.
+하지만 항상 그런 것은 아닙니다. 일부 모델은 마지막 은닉 상태가 반환될 때 정규화를 적용하거나 다른 후속 프로세스를 적용합니다.
+
+
+
+
+일반적으로 사용할 때와 동일하게 각 속성들에 접근할 수 있으며, 모델이 해당 속성을 반환하지 않은 경우 `None`이 반환됩니다. 예시에서는 `outputs.loss`는 모델에서 계산한 손실이고 `outputs.attentions`는 `None`입니다.
+
+`outputs` 객체를 튜플로 간주할 때는 `None` 값이 없는 속성만 고려합니다.
+예시에서는 `loss`와 `logits`라는 두 개의 요소가 있습니다. 그러므로,
+
+```python
+outputs[:2]
+```
+
+는 `(outputs.loss, outputs.logits)` 튜플을 반환합니다.
+
+`outputs` 객체를 딕셔너리로 간주할 때는 `None` 값이 없는 속성만 고려합니다.
+예시에는 `loss`와 `logits`라는 두 개의 키가 있습니다.
+
+여기서부터는 두 가지 이상의 모델 유형에서 사용되는 일반 모델 출력을 다룹니다. 구체적인 출력 유형은 해당 모델 페이지에 문서화되어 있습니다.
+
+## ModelOutput[[transformers.utils.ModelOutput]]
+
+[[autodoc]] utils.ModelOutput
+ - to_tuple
+
+## BaseModelOutput[[transformers.BaseModelOutput]]
+
+[[autodoc]] modeling_outputs.BaseModelOutput
+
+## BaseModelOutputWithPooling[[transformers.modeling_outputs.BaseModelOutputWithPooling]]
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPooling
+
+## BaseModelOutputWithCrossAttentions[[transformers.modeling_outputs.BaseModelOutputWithCrossAttentions]]
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithCrossAttentions
+
+## BaseModelOutputWithPoolingAndCrossAttentions[[transformers.modeling_outputs.BaseModelOutputWithPoolingAndCrossAttentions]]
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPoolingAndCrossAttentions
+
+## BaseModelOutputWithPast[[transformers.modeling_outputs.BaseModelOutputWithPast]]
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPast
+
+## BaseModelOutputWithPastAndCrossAttentions[[transformers.modeling_outputs.BaseModelOutputWithPastAndCrossAttentions]]
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPastAndCrossAttentions
+
+## Seq2SeqModelOutput[[transformers.modeling_outputs.Seq2SeqModelOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqModelOutput
+
+## CausalLMOutput[[transformers.modeling_outputs.CausalLMOutput]]
+
+[[autodoc]] modeling_outputs.CausalLMOutput
+
+## CausalLMOutputWithCrossAttentions[[transformers.modeling_outputs.CausalLMOutputWithCrossAttentions]]
+
+[[autodoc]] modeling_outputs.CausalLMOutputWithCrossAttentions
+
+## CausalLMOutputWithPast[[transformers.modeling_outputs.CausalLMOutputWithPast]]
+
+[[autodoc]] modeling_outputs.CausalLMOutputWithPast
+
+## MaskedLMOutput[[transformers.modeling_outputs.MaskedLMOutput]]
+
+[[autodoc]] modeling_outputs.MaskedLMOutput
+
+## Seq2SeqLMOutput[[transformers.modeling_outputs.Seq2SeqLMOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqLMOutput
+
+## NextSentencePredictorOutput[[transformers.modeling_outputs.NextSentencePredictorOutput]]
+
+[[autodoc]] modeling_outputs.NextSentencePredictorOutput
+
+## SequenceClassifierOutput[[transformers.modeling_outputs.SequenceClassifierOutput]]
+
+[[autodoc]] modeling_outputs.SequenceClassifierOutput
+
+## Seq2SeqSequenceClassifierOutput[[transformers.modeling_outputs.Seq2SeqSequenceClassifierOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqSequenceClassifierOutput
+
+## MultipleChoiceModelOutput[[transformers.modeling_outputs.MultipleChoiceModelOutput]]
+
+[[autodoc]] modeling_outputs.MultipleChoiceModelOutput
+
+## TokenClassifierOutput[[transformers.modeling_outputs.TokenClassifierOutput]]
+
+[[autodoc]] modeling_outputs.TokenClassifierOutput
+
+## QuestionAnsweringModelOutput[[transformers.modeling_outputs.QuestionAnsweringModelOutput]]
+
+[[autodoc]] modeling_outputs.QuestionAnsweringModelOutput
+
+## Seq2SeqQuestionAnsweringModelOutput[[transformers.modeling_outputs.Seq2SeqQuestionAnsweringModelOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqQuestionAnsweringModelOutput
+
+## Seq2SeqSpectrogramOutput[[transformers.modeling_outputs.Seq2SeqSpectrogramOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqSpectrogramOutput
+
+## SemanticSegmenterOutput[[transformers.modeling_outputs.SemanticSegmenterOutput]]
+
+[[autodoc]] modeling_outputs.SemanticSegmenterOutput
+
+## ImageClassifierOutput[[transformers.modeling_outputs.ImageClassifierOutput]]
+
+[[autodoc]] modeling_outputs.ImageClassifierOutput
+
+## ImageClassifierOutputWithNoAttention[[transformers.modeling_outputs.ImageClassifierOutputWithNoAttention]]
+
+[[autodoc]] modeling_outputs.ImageClassifierOutputWithNoAttention
+
+## DepthEstimatorOutput[[transformers.modeling_outputs.DepthEstimatorOutput]]
+
+[[autodoc]] modeling_outputs.DepthEstimatorOutput
+
+## Wav2Vec2BaseModelOutput[[transformers.modeling_outputs.Wav2Vec2BaseModelOutput]]
+
+[[autodoc]] modeling_outputs.Wav2Vec2BaseModelOutput
+
+## XVectorOutput[[transformers.modeling_outputs.XVectorOutput]]
+
+[[autodoc]] modeling_outputs.XVectorOutput
+
+## Seq2SeqTSModelOutput[[transformers.modeling_outputs.Seq2SeqTSModelOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqTSModelOutput
+
+## Seq2SeqTSPredictionOutput[[transformers.modeling_outputs.Seq2SeqTSPredictionOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqTSPredictionOutput
+
+## SampleTSPredictionOutput[[transformers.modeling_outputs.SampleTSPredictionOutput]]
+
+[[autodoc]] modeling_outputs.SampleTSPredictionOutput
+
+## TFBaseModelOutput[[transformers.modeling_outputs.TFBaseModelOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutput
+
+## TFBaseModelOutputWithPooling[[transformers.modeling_tf_outputs.TFBaseModelOutputWithPooling]]
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPooling
+
+## TFBaseModelOutputWithPoolingAndCrossAttentions[[transformers.modeling_tf_outputs.TFBaseModelOutputWithPoolingAndCrossAttentions]]
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPoolingAndCrossAttentions
+
+## TFBaseModelOutputWithPast[[transformers.modeling_tf_outputs.TFBaseModelOutputWithPast]]
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPast
+
+## TFBaseModelOutputWithPastAndCrossAttentions[[transformers.modeling_tf_outputs.TFBaseModelOutputWithPastAndCrossAttentions]]
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPastAndCrossAttentions
+
+## TFSeq2SeqModelOutput[[transformers.modeling_tf_outputs.TFSeq2SeqModelOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqModelOutput
+
+## TFCausalLMOutput[[transformers.modeling_tf_outputs.TFCausalLMOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFCausalLMOutput
+
+## TFCausalLMOutputWithCrossAttentions[[transformers.modeling_tf_outputs.TFCausalLMOutputWithCrossAttentions]]
+
+[[autodoc]] modeling_tf_outputs.TFCausalLMOutputWithCrossAttentions
+
+## TFCausalLMOutputWithPast[[transformers.modeling_tf_outputs.TFCausalLMOutputWithPast]]
+
+[[autodoc]] modeling_tf_outputs.TFCausalLMOutputWithPast
+
+## TFMaskedLMOutput[[transformers.modeling_tf_outputs.TFMaskedLMOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFMaskedLMOutput
+
+## TFSeq2SeqLMOutput[[transformers.modeling_tf_outputs.TFSeq2SeqLMOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqLMOutput
+
+## TFNextSentencePredictorOutput[[transformers.modeling_tf_outputs.TFNextSentencePredictorOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFNextSentencePredictorOutput
+
+## TFSequenceClassifierOutput[[transformers.modeling_tf_outputs.TFSequenceClassifierOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFSequenceClassifierOutput
+
+## TFSeq2SeqSequenceClassifierOutput[[transformers.modeling_tf_outputs.TFSeq2SeqSequenceClassifierOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqSequenceClassifierOutput
+
+## TFMultipleChoiceModelOutput[[transformers.modeling_tf_outputs.TFMultipleChoiceModelOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFMultipleChoiceModelOutput
+
+## TFTokenClassifierOutput[[transformers.modeling_tf_outputs.TFTokenClassifierOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFTokenClassifierOutput
+
+## TFQuestionAnsweringModelOutput[[transformers.modeling_tf_outputs.TFQuestionAnsweringModelOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFQuestionAnsweringModelOutput
+
+## TFSeq2SeqQuestionAnsweringModelOutput[[transformers.modeling_tf_outputs.TFSeq2SeqQuestionAnsweringModelOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqQuestionAnsweringModelOutput
+
+## FlaxBaseModelOutput[[transformers.modeling_flax_outputs.FlaxBaseModelOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutput
+
+## FlaxBaseModelOutputWithPast[[transformers.modeling_flax_outputs.FlaxBaseModelOutputWithPast]]
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutputWithPast
+
+## FlaxBaseModelOutputWithPooling[[transformers.modeling_flax_outputs.FlaxBaseModelOutputWithPooling]]
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutputWithPooling
+
+## FlaxBaseModelOutputWithPastAndCrossAttentions[[transformers.modeling_flax_outputs.FlaxBaseModelOutputWithPastAndCrossAttentions]]
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutputWithPastAndCrossAttentions
+
+## FlaxSeq2SeqModelOutput[[transformers.modeling_flax_outputs.FlaxSeq2SeqModelOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqModelOutput
+
+## FlaxCausalLMOutputWithCrossAttentions[[transformers.modeling_flax_outputs.FlaxCausalLMOutputWithCrossAttentions]]
+
+[[autodoc]] modeling_flax_outputs.FlaxCausalLMOutputWithCrossAttentions
+
+## FlaxMaskedLMOutput[[transformers.modeling_flax_outputs.FlaxMaskedLMOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxMaskedLMOutput
+
+## FlaxSeq2SeqLMOutput[[transformers.modeling_flax_outputs.FlaxSeq2SeqLMOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqLMOutput
+
+## FlaxNextSentencePredictorOutput[[transformers.modeling_flax_outputs.FlaxNextSentencePredictorOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxNextSentencePredictorOutput
+
+## FlaxSequenceClassifierOutput[[transformers.modeling_flax_outputs.FlaxSequenceClassifierOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxSequenceClassifierOutput
+
+## FlaxSeq2SeqSequenceClassifierOutput[[transformers.modeling_flax_outputs.FlaxSeq2SeqSequenceClassifierOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqSequenceClassifierOutput
+
+## FlaxMultipleChoiceModelOutput[[transformers.modeling_flax_outputs.FlaxMultipleChoiceModelOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxMultipleChoiceModelOutput
+
+## FlaxTokenClassifierOutput[[transformers.modeling_flax_outputs.FlaxTokenClassifierOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxTokenClassifierOutput
+
+## FlaxQuestionAnsweringModelOutput[[transformers.modeling_flax_outputs.FlaxQuestionAnsweringModelOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxQuestionAnsweringModelOutput
+
+## FlaxSeq2SeqQuestionAnsweringModelOutput[[transformers.modeling_flax_outputs.FlaxSeq2SeqQuestionAnsweringModelOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqQuestionAnsweringModelOutput
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/quantization.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/quantization.md
new file mode 100644
index 0000000000000000000000000000000000000000..6f793f2210741788cf67a2e2a8232c654ea77484
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/quantization.md
@@ -0,0 +1,75 @@
+
+
+# 양자화[[quantization]]
+
+
+
+양자화 기법은 가중치와 활성화를 8비트 정수(int8)와 같은 더 낮은 정밀도의 데이터 타입으로 표현함으로써 메모리와 계산 비용을 줄입니다. 이를 통해 일반적으로는 메모리에 올릴 수 없는 더 큰 모델을 로드할 수 있고, 추론 속도를 높일 수 있습니다. Transformers는 AWQ와 GPTQ 양자화 알고리즘을 지원하며, bitsandbytes를 통해 8비트와 4비트 양자화를 지원합니다.
+Transformers에서 지원되지 않는 양자화 기법들은 [`HfQuantizer`] 클래스를 통해 추가될 수 있습니다.
+
+
+
+모델을 양자화하는 방법은 이 [양자화](../quantization) 가이드를 통해 배울 수 있습니다.
+
+
+
+## QuantoConfig[[transformers.QuantoConfig]]
+
+[[autodoc]] QuantoConfig
+
+## AqlmConfig[[transformers.AqlmConfig]]
+
+[[autodoc]] AqlmConfig
+
+## VptqConfig[[transformers.VptqConfig]]
+
+[[autodoc]] VptqConfig
+
+## AwqConfig[[transformers.AwqConfig]]
+
+[[autodoc]] AwqConfig
+
+## EetqConfig[[transformers.EetqConfig]]
+[[autodoc]] EetqConfig
+
+## GPTQConfig[[transformers.GPTQConfig]]
+
+[[autodoc]] GPTQConfig
+
+## BitsAndBytesConfig[[#transformers.BitsAndBytesConfig]]
+
+[[autodoc]] BitsAndBytesConfig
+
+## HfQuantizer[[transformers.quantizers.HfQuantizer]]
+
+[[autodoc]] quantizers.base.HfQuantizer
+
+## HqqConfig[[transformers.HqqConfig]]
+
+[[autodoc]] HqqConfig
+
+## FbgemmFp8Config[[transformers.FbgemmFp8Config]]
+
+[[autodoc]] FbgemmFp8Config
+
+## CompressedTensorsConfig[[transformers.CompressedTensorsConfig]]
+
+[[autodoc]] CompressedTensorsConfig
+
+## TorchAoConfig[[transformers.TorchAoConfig]]
+
+[[autodoc]] TorchAoConfig
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/text_generation.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/text_generation.md
new file mode 100644
index 0000000000000000000000000000000000000000..917d995e6ec15c4a642e2c3bf4c5fc7b865fdb85
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/text_generation.md
@@ -0,0 +1,56 @@
+
+
+# 생성 [[generation]]
+
+각 프레임워크에는 해당하는 `GenerationMixin` 클래스에서 구현된 텍스트 생성을 위한 generate 메소드가 있습니다:
+
+- PyTorch에서는 [`~generation.GenerationMixin.generate`]가 [`~generation.GenerationMixin`]에 구현되어 있습니다.
+- TensorFlow에서는 [`~generation.TFGenerationMixin.generate`]가 [`~generation.TFGenerationMixin`]에 구현되어 있습니다.
+- Flax/JAX에서는 [`~generation.FlaxGenerationMixin.generate`]가 [`~generation.FlaxGenerationMixin`]에 구현되어 있습니다.
+
+사용하는 프레임워크에 상관없이, generate 메소드는 [`~generation.GenerationConfig`] 클래스 인스턴스로 매개변수화 할 수 있습니다. generate 메소드의 동작을 제어하는 모든 생성 매개변수 목록을 확인하려면 이 클래스를 참조하세요.
+
+모델의 생성 설정을 어떻게 확인하고, 기본값이 무엇인지, 매개변수를 어떻게 임시로 변경하는지, 그리고 사용자 지정 생성 설정을 만들고 저장하는 방법을 배우려면 [텍스트 생성 전략 가이드](../generation_strategies)를 참조하세요. 이 가이드는 토큰 스트리밍과 같은 관련 기능을 사용하는 방법도 설명합니다.
+
+## GenerationConfig [[transformers.GenerationConfig]]
+
+[[autodoc]] generation.GenerationConfig
+ - from_pretrained
+ - from_model_config
+ - save_pretrained
+ - update
+ - validate
+ - get_generation_mode
+
+[[autodoc]] generation.WatermarkingConfig
+
+## GenerationMixin [[transformers.GenerationMixin]]
+
+[[autodoc]] generation.GenerationMixin
+ - generate
+ - compute_transition_scores
+
+## TFGenerationMixin [[transformers.TFGenerationMixin]]
+
+[[autodoc]] generation.TFGenerationMixin
+ - generate
+ - compute_transition_scores
+
+## FlaxGenerationMixin [[transformers.FlaxGenerationMixin]]
+
+[[autodoc]] generation.FlaxGenerationMixin
+ - generate
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/trainer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/trainer.md
new file mode 100644
index 0000000000000000000000000000000000000000..23eda74a8bd669c16fcb3ebdbd21ea7cd8d6cd65
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/main_classes/trainer.md
@@ -0,0 +1,52 @@
+
+
+# Trainer [[trainer]]
+
+[`Trainer`] 클래스는 PyTorch에서 완전한 기능(feature-complete)의 훈련을 위한 API를 제공하며, 다중 GPU/TPU에서의 분산 훈련, [NVIDIA GPU](https://nvidia.github.io/apex/), [AMD GPU](https://rocm.docs.amd.com/en/latest/rocm.html)를 위한 혼합 정밀도, 그리고 PyTorch의 [`torch.amp`](https://pytorch.org/docs/stable/amp.html)를 지원합니다. [`Trainer`]는 모델의 훈련 방식을 커스터마이즈할 수 있는 다양한 옵션을 제공하는 [`TrainingArguments`] 클래스와 함께 사용됩니다. 이 두 클래스는 함께 완전한 훈련 API를 제공합니다.
+
+[`Seq2SeqTrainer`]와 [`Seq2SeqTrainingArguments`]는 [`Trainer`]와 [`TrainingArguments`] 클래스를 상속하며, 요약이나 번역과 같은 시퀀스-투-시퀀스 작업을 위한 모델 훈련에 적합하게 조정되어 있습니다.
+
+
+
+[`Trainer`] 클래스는 🤗 Transformers 모델에 최적화되어 있으며, 다른 모델과 함께 사용될 때 예상치 못한 동작을 하게 될 수 있습니다. 자신만의 모델을 사용할 때는 다음을 확인하세요:
+
+- 모델은 항상 튜플이나 [`~utils.ModelOutput`]의 서브클래스를 반환해야 합니다.
+- 모델은 `labels` 인자가 제공되면 손실을 계산할 수 있고, 모델이 튜플을 반환하는 경우 그 손실이 튜플의 첫 번째 요소로 반환되어야 합니다.
+- 모델은 여러 개의 레이블 인자를 수용할 수 있어야 하며, [`Trainer`]에게 이름을 알리기 위해 [`TrainingArguments`]에서 `label_names`를 사용하지만, 그 중 어느 것도 `"label"`로 명명되어서는 안 됩니다.
+
+
+
+## Trainer [[transformers.Trainer]]
+
+[[autodoc]] Trainer
+ - all
+
+## Seq2SeqTrainer [[transformers.Seq2SeqTrainer]]
+
+[[autodoc]] Seq2SeqTrainer
+ - evaluate
+ - predict
+
+## TrainingArguments [[transformers.TrainingArguments]]
+
+[[autodoc]] TrainingArguments
+ - all
+
+## Seq2SeqTrainingArguments [[transformers.Seq2SeqTrainingArguments]]
+
+[[autodoc]] Seq2SeqTrainingArguments
+ - all
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/altclip.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/altclip.md
new file mode 100644
index 0000000000000000000000000000000000000000..1236bcc9aaa7da8da5fb4820bb87b3f9413cb805
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/altclip.md
@@ -0,0 +1,78 @@
+# AltCLIP
+
+## 개요[[overview]]
+
+AltCLIP 모델은 Zhongzhi Chen, Guang Liu, Bo-Wen Zhang, Fulong Ye, Qinghong Yang, Ledell Wu의 [AltCLIP: Altering the Language Encoder in CLIP for Extended Language Capabilities](https://arxiv.org/abs/2211.06679v2) 논문에서 제안되었습니다. AltCLIP(CLIP의 언어 인코더를 변경하여 언어 기능 확장)은 다양한 이미지-텍스트 및 텍스트-텍스트 쌍으로 훈련된 신경망입니다. CLIP의 텍스트 인코더를 사전 훈련된 다국어 텍스트 인코더 XLM-R로 교체하여, 거의 모든 작업에서 CLIP과 유사한 성능을 얻을 수 있었으며, 원래 CLIP의 다국어 이해와 같은 기능도 확장되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*본 연구에서는 강력한 이중 언어 멀티모달 표현 모델을 훈련하는 개념적으로 간단하고 효과적인 방법을 제시합니다. OpenAI에서 출시한 사전 훈련된 멀티모달 표현 모델 CLIP에서 시작하여, 그 텍스트 인코더를 사전 훈련된 다국어 텍스트 인코더 XLM-R로 교체하고, 교사 학습과 대조 학습으로 구성된 2단계 훈련 스키마를 통해 언어와 이미지 표현을 정렬했습니다. 우리는 광범위한 작업 평가를 통해 우리의 방법을 검증했습니다. ImageNet-CN, Flicker30k-CN, COCO-CN을 포함한 여러 작업에서 새로운 최고 성능을 달성했으며, 거의 모든 작업에서 CLIP과 유사한 성능을 얻었습니다. 이는 CLIP의 텍스트 인코더를 단순히 변경하여 다국어 이해와 같은 확장 기능을 얻을 수 있음을 시사합니다.*
+
+이 모델은 [jongjyh](https://huggingface.co/jongjyh)에 의해 기여되었습니다.
+
+## 사용 팁과 예제[[usage-tips-and-example]]
+
+AltCLIP의 사용법은 CLIP과 매우 유사하며, 차이점은 텍스트 인코더에 있습니다. 일반적인 어텐션 대신 양방향 어텐션을 사용하며, XLM-R의 [CLS] 토큰을 사용하여 텍스트 임베딩을 나타냅니다.
+
+AltCLIP은 멀티모달 비전 및 언어 모델입니다. 이미지와 텍스트 간의 유사성 계산 및 제로샷 이미지 분류에 사용할 수 있습니다. AltCLIP은 ViT와 같은 트랜스포머를 사용하여 시각적 특징을 얻고, 양방향 언어 모델을 사용하여 텍스트 특징을 얻습니다. 이후 텍스트와 시각적 특징 모두 동일한 차원의 잠재 공간으로 투사됩니다. 투사된 이미지와 텍스트 특징 간의 내적을 유사도 점수로 사용합니다.
+
+이미지를 트랜스포머 인코더에 입력하기 위해, 각 이미지를 일정한 크기의 겹치지 않는 패치 시퀀스로 분할한 뒤, 이를 선형 임베딩합니다. 전체 이미지를 나타내기 위해 [CLS] 토큰이 추가됩니다. 저자들은 절대 위치 임베딩도 추가하여 결과 벡터 시퀀스를 표준 트랜스포머 인코더에 입력합니다. [`CLIPImageProcessor`]는 모델을 위해 이미지를 크기 조정하고 정규화하는 데 사용할 수 있습니다.
+
+[`AltCLIPProcessor`]는 [`CLIPImageProcessor`]와 [`XLMRobertaTokenizer`]를 하나의 인스턴스로 묶어 텍스트를 인코딩하고 이미지를 준비합니다. 다음 예제는 [`AltCLIPProcessor`]와 [`AltCLIPModel`]을 사용하여 이미지와 텍스트 간의 유사성 점수를 얻는 방법을 보여줍니다.
+```python
+>>> from PIL import Image
+>>> import requests
+
+>>> from transformers import AltCLIPModel, AltCLIPProcessor
+
+>>> model = AltCLIPModel.from_pretrained("BAAI/AltCLIP")
+>>> processor = AltCLIPProcessor.from_pretrained("BAAI/AltCLIP")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> inputs = processor(text=["a photo of a cat", "a photo of a dog"], images=image, return_tensors="pt", padding=True)
+
+>>> outputs = model(**inputs)
+>>> logits_per_image = outputs.logits_per_image # 이미지-텍스트 유사도 점수
+>>> probs = logits_per_image.softmax(dim=1) # 라벨 마다 확률을 얻기 위해 softmax 적용
+```
+
+
+이 모델은 `CLIPModel`을 기반으로 하므로, 원래 CLIP처럼 사용할 수 있습니다.
+
+
+
+## AltCLIPConfig
+
+[[autodoc]] AltCLIPConfig
+ - from_text_vision_configs
+
+## AltCLIPTextConfig
+
+[[autodoc]] AltCLIPTextConfig
+
+## AltCLIPVisionConfig
+
+[[autodoc]] AltCLIPVisionConfig
+
+## AltCLIPProcessor
+
+[[autodoc]] AltCLIPProcessor
+
+## AltCLIPModel
+
+[[autodoc]] AltCLIPModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## AltCLIPTextModel
+
+[[autodoc]] AltCLIPTextModel
+ - forward
+
+## AltCLIPVisionModel
+
+[[autodoc]] AltCLIPVisionModel
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/auto.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/auto.md
new file mode 100644
index 0000000000000000000000000000000000000000..cda00adc33a663c1b426a61f10ace8d708936da8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/auto.md
@@ -0,0 +1,375 @@
+
+
+# Auto 클래스[[auto-classes]]
+
+많은 경우, 사용하려는 아키텍처는 `from_pretrained()` 메소드에서 제공하는 사전 훈련된 모델의 이름이나 경로로부터 유추할 수 있습니다. AutoClasses는 이 작업을 위해 존재하며, 사전 학습된 모델 가중치/구성/단어사전에 대한 이름/경로를 제공하면 자동으로 관련 모델을 가져오도록 도와줍니다.
+
+[`AutoConfig`], [`AutoModel`], [`AutoTokenizer`] 중 하나를 인스턴스화하면 해당 아키텍처의 클래스를 직접 생성합니다. 예를 들어,
+
+
+```python
+model = AutoModel.from_pretrained("google-bert/bert-base-cased")
+```
+
+위 코드는 [`BertModel`]의 인스턴스인 모델을 생성합니다.
+
+각 작업에 대해 하나의 `AutoModel` 클래스가 있으며, 각각의 백엔드(PyTorch, TensorFlow 또는 Flax)에 해당하는 클래스가 존재합니다.
+
+## 자동 클래스 확장[[extending-the-auto-classes]]
+
+각 자동 클래스는 사용자의 커스텀 클래스로 확장될 수 있는 메소드를 가지고 있습니다. 예를 들어, `NewModel`이라는 커스텀 모델 클래스를 정의했다면, `NewModelConfig`를 준비한 후 다음과 같이 자동 클래스에 추가할 수 있습니다:
+
+```python
+from transformers import AutoConfig, AutoModel
+
+AutoConfig.register("new-model", NewModelConfig)
+AutoModel.register(NewModelConfig, NewModel)
+```
+
+이후에는 일반적으로 자동 클래스를 사용하는 것처럼 사용할 수 있습니다!
+
+
+
+만약 `NewModelConfig`가 [`~transformers.PretrainedConfig`]의 서브클래스라면, 해당 `model_type` 속성이 등록할 때 사용하는 키(여기서는 `"new-model"`)와 동일하게 설정되어 있는지 확인하세요.
+
+마찬가지로, `NewModel`이 [`PreTrainedModel`]의 서브클래스라면, 해당 `config_class` 속성이 등록할 때 사용하는 클래스(여기서는 `NewModelConfig`)와 동일하게 설정되어 있는지 확인하세요.
+
+
+
+## AutoConfig[[transformers.AutoConfig]]
+
+[[autodoc]] AutoConfig
+
+## AutoTokenizer[[transformers.AutoTokenizer]]
+
+[[autodoc]] AutoTokenizer
+
+## AutoFeatureExtractor[[transformers.AutoFeatureExtractor]]
+
+[[autodoc]] AutoFeatureExtractor
+
+## AutoImageProcessor[[transformers.AutoImageProcessor]]
+
+[[autodoc]] AutoImageProcessor
+
+## AutoProcessor[[transformers.AutoProcessor]]
+
+[[autodoc]] AutoProcessor
+
+## 일반적인 모델 클래스[[generic-model-classes]]
+
+다음 자동 클래스들은 특정 헤드 없이 기본 모델 클래스를 인스턴스화하는 데 사용할 수 있습니다.
+
+### AutoModel[[transformers.AutoModel]]
+
+[[autodoc]] AutoModel
+
+### TFAutoModel[[transformers.TFAutoModel]]
+
+[[autodoc]] TFAutoModel
+
+### FlaxAutoModel[[transformers.FlaxAutoModel]]
+
+[[autodoc]] FlaxAutoModel
+
+## 일반적인 사전 학습 클래스[[generic-pretraining-classes]]
+
+다음 자동 클래스들은 사전 훈련 헤드가 포함된 모델을 인스턴스화하는 데 사용할 수 있습니다.
+
+### AutoModelForPreTraining[[transformers.AutoModelForPreTraining]]
+
+[[autodoc]] AutoModelForPreTraining
+
+### TFAutoModelForPreTraining[[transformers.TFAutoModelForPreTraining]]
+
+[[autodoc]] TFAutoModelForPreTraining
+
+### FlaxAutoModelForPreTraining[[transformers.FlaxAutoModelForPreTraining]]
+
+[[autodoc]] FlaxAutoModelForPreTraining
+
+## 자연어 처리[[natural-language-processing]]
+
+다음 자동 클래스들은 아래의 자연어 처리 작업에 사용할 수 있습니다.
+
+### AutoModelForCausalLM[[transformers.AutoModelForCausalLM]]
+
+[[autodoc]] AutoModelForCausalLM
+
+### TFAutoModelForCausalLM[[transformers.TFAutoModelForCausalLM]]
+
+[[autodoc]] TFAutoModelForCausalLM
+
+### FlaxAutoModelForCausalLM[[transformers.FlaxAutoModelForCausalLM]]
+
+[[autodoc]] FlaxAutoModelForCausalLM
+
+### AutoModelForMaskedLM[[transformers.AutoModelForMaskedLM]]
+
+[[autodoc]] AutoModelForMaskedLM
+
+### TFAutoModelForMaskedLM[[transformers.TFAutoModelForMaskedLM]]
+
+[[autodoc]] TFAutoModelForMaskedLM
+
+### FlaxAutoModelForMaskedLM[[transformers.FlaxAutoModelForMaskedLM]]
+
+[[autodoc]] FlaxAutoModelForMaskedLM
+
+### AutoModelForMaskGeneration[[transformers.AutoModelForMaskGeneration]]
+
+[[autodoc]] AutoModelForMaskGeneration
+
+### TFAutoModelForMaskGeneration[[transformers.TFAutoModelForMaskGeneration]]
+
+[[autodoc]] TFAutoModelForMaskGeneration
+
+### AutoModelForSeq2SeqLM[[transformers.AutoModelForSeq2SeqLM]]
+
+[[autodoc]] AutoModelForSeq2SeqLM
+
+### TFAutoModelForSeq2SeqLM[[transformers.TFAutoModelForSeq2SeqLM]]
+
+[[autodoc]] TFAutoModelForSeq2SeqLM
+
+### FlaxAutoModelForSeq2SeqLM[[transformers.FlaxAutoModelForSeq2SeqLM]]
+
+[[autodoc]] FlaxAutoModelForSeq2SeqLM
+
+### AutoModelForSequenceClassification[[transformers.AutoModelForSequenceClassification]]
+
+[[autodoc]] AutoModelForSequenceClassification
+
+### TFAutoModelForSequenceClassification[[transformers.TFAutoModelForSequenceClassification]]
+
+[[autodoc]] TFAutoModelForSequenceClassification
+
+### FlaxAutoModelForSequenceClassification[[transformers.FlaxAutoModelForSequenceClassification]]
+
+[[autodoc]] FlaxAutoModelForSequenceClassification
+
+### AutoModelForMultipleChoice[[transformers.AutoModelForMultipleChoice]]
+
+[[autodoc]] AutoModelForMultipleChoice
+
+### TFAutoModelForMultipleChoice[[transformers.TFAutoModelForMultipleChoice]]
+
+[[autodoc]] TFAutoModelForMultipleChoice
+
+### FlaxAutoModelForMultipleChoice[[transformers.FlaxAutoModelForMultipleChoice]]
+
+[[autodoc]] FlaxAutoModelForMultipleChoice
+
+### AutoModelForNextSentencePrediction[[transformers.AutoModelForNextSentencePrediction]]
+
+[[autodoc]] AutoModelForNextSentencePrediction
+
+### TFAutoModelForNextSentencePrediction[[transformers.TFAutoModelForNextSentencePrediction]]
+
+[[autodoc]] TFAutoModelForNextSentencePrediction
+
+### FlaxAutoModelForNextSentencePrediction[[transformers.FlaxAutoModelForNextSentencePrediction]]
+
+[[autodoc]] FlaxAutoModelForNextSentencePrediction
+
+### AutoModelForTokenClassification[[transformers.AutoModelForTokenClassification]]
+
+[[autodoc]] AutoModelForTokenClassification
+
+### TFAutoModelForTokenClassification[[transformers.TFAutoModelForTokenClassification]]
+
+[[autodoc]] TFAutoModelForTokenClassification
+
+### FlaxAutoModelForTokenClassification[[transformers.FlaxAutoModelForTokenClassification]]
+
+[[autodoc]] FlaxAutoModelForTokenClassification
+
+### AutoModelForQuestionAnswering[[transformers.AutoModelForQuestionAnswering]]
+
+[[autodoc]] AutoModelForQuestionAnswering
+
+### TFAutoModelForQuestionAnswering[[transformers.TFAutoModelForQuestionAnswering]]
+
+[[autodoc]] TFAutoModelForQuestionAnswering
+
+### FlaxAutoModelForQuestionAnswering[[transformers.FlaxAutoModelForQuestionAnswering]]
+
+[[autodoc]] FlaxAutoModelForQuestionAnswering
+
+### AutoModelForTextEncoding[[transformers.AutoModelForTextEncoding]]
+
+[[autodoc]] AutoModelForTextEncoding
+
+### TFAutoModelForTextEncoding[[transformers.TFAutoModelForTextEncoding]]
+
+[[autodoc]] TFAutoModelForTextEncoding
+
+## 컴퓨터 비전[[computer-vision]]
+
+다음 자동 클래스들은 아래의 컴퓨터 비전 작업에 사용할 수 있습니다.
+
+### AutoModelForDepthEstimation[[transformers.AutoModelForDepthEstimation]]
+
+[[autodoc]] AutoModelForDepthEstimation
+
+### AutoModelForImageClassification[[transformers.AutoModelForImageClassification]]
+
+[[autodoc]] AutoModelForImageClassification
+
+### TFAutoModelForImageClassification[[transformers.TFAutoModelForImageClassification]]
+
+[[autodoc]] TFAutoModelForImageClassification
+
+### FlaxAutoModelForImageClassification[[transformers.FlaxAutoModelForImageClassification]]
+
+[[autodoc]] FlaxAutoModelForImageClassification
+
+### AutoModelForVideoClassification[[transformers.AutoModelForVideoClassification]]
+
+[[autodoc]] AutoModelForVideoClassification
+
+### AutoModelForKeypointDetection[[transformers.AutoModelForKeypointDetection]]
+
+[[autodoc]] AutoModelForKeypointDetection
+
+### AutoModelForMaskedImageModeling[[transformers.AutoModelForMaskedImageModeling]]
+
+[[autodoc]] AutoModelForMaskedImageModeling
+
+### TFAutoModelForMaskedImageModeling[[transformers.TFAutoModelForMaskedImageModeling]]
+
+[[autodoc]] TFAutoModelForMaskedImageModeling
+
+### AutoModelForObjectDetection[[transformers.AutoModelForObjectDetection]]
+
+[[autodoc]] AutoModelForObjectDetection
+
+### AutoModelForImageSegmentation[[transformers.AutoModelForImageSegmentation]]
+
+[[autodoc]] AutoModelForImageSegmentation
+
+### AutoModelForImageToImage[[transformers.AutoModelForImageToImage]]
+
+[[autodoc]] AutoModelForImageToImage
+
+### AutoModelForSemanticSegmentation[[transformers.AutoModelForSemanticSegmentation]]
+
+[[autodoc]] AutoModelForSemanticSegmentation
+
+### TFAutoModelForSemanticSegmentation[[transformers.TFAutoModelForSemanticSegmentation]]
+
+[[autodoc]] TFAutoModelForSemanticSegmentation
+
+### AutoModelForInstanceSegmentation[[transformers.AutoModelForInstanceSegmentation]]
+
+[[autodoc]] AutoModelForInstanceSegmentation
+
+### AutoModelForUniversalSegmentation[[transformers.AutoModelForUniversalSegmentation]]
+
+[[autodoc]] AutoModelForUniversalSegmentation
+
+### AutoModelForZeroShotImageClassification[[transformers.AutoModelForZeroShotImageClassification]]
+
+[[autodoc]] AutoModelForZeroShotImageClassification
+
+### TFAutoModelForZeroShotImageClassification[[transformers.TFAutoModelForZeroShotImageClassification]]
+
+[[autodoc]] TFAutoModelForZeroShotImageClassification
+
+### AutoModelForZeroShotObjectDetection[[transformers.AutoModelForZeroShotObjectDetection]]
+
+[[autodoc]] AutoModelForZeroShotObjectDetection
+
+## 오디오[[audio]]
+
+다음 자동 클래스들은 아래의 오디오 작업에 사용할 수 있습니다.
+
+### AutoModelForAudioClassification[[transformers.AutoModelForAudioClassification]]
+
+[[autodoc]] AutoModelForAudioClassification
+
+### TFAutoModelForAudioClassification[[transformers.TFAutoModelForAudioClassification]]
+
+[[autodoc]] TFAutoModelForAudioClassification
+
+### AutoModelForAudioFrameClassification[[transformers.AutoModelForAudioFrameClassification]]
+
+[[autodoc]] AutoModelForAudioFrameClassification
+
+### AutoModelForCTC[[transformers.AutoModelForCTC]]
+
+[[autodoc]] AutoModelForCTC
+
+### AutoModelForSpeechSeq2Seq[[transformers.AutoModelForSpeechSeq2Seq]]
+
+[[autodoc]] AutoModelForSpeechSeq2Seq
+
+### TFAutoModelForSpeechSeq2Seq[[transformers.TFAutoModelForSpeechSeq2Seq]]
+
+[[autodoc]] TFAutoModelForSpeechSeq2Seq
+
+### FlaxAutoModelForSpeechSeq2Seq[[transformers.FlaxAutoModelForSpeechSeq2Seq]]
+
+[[autodoc]] FlaxAutoModelForSpeechSeq2Seq
+
+### AutoModelForAudioXVector[[transformers.AutoModelForAudioXVector]]
+
+[[autodoc]] AutoModelForAudioXVector
+
+### AutoModelForTextToSpectrogram[[transformers.AutoModelForTextToSpectrogram]]
+
+[[autodoc]] AutoModelForTextToSpectrogram
+
+### AutoModelForTextToWaveform[[transformers.AutoModelForTextToWaveform]]
+
+[[autodoc]] AutoModelForTextToWaveform
+
+## 멀티모달[[multimodal]]
+
+다음 자동 클래스들은 아래의 멀티모달 작업에 사용할 수 있습니다.
+
+### AutoModelForTableQuestionAnswering[[transformers.AutoModelForTableQuestionAnswering]]
+
+[[autodoc]] AutoModelForTableQuestionAnswering
+
+### TFAutoModelForTableQuestionAnswering[[transformers.TFAutoModelForTableQuestionAnswering]]
+
+[[autodoc]] TFAutoModelForTableQuestionAnswering
+
+### AutoModelForDocumentQuestionAnswering[[transformers.AutoModelForDocumentQuestionAnswering]]
+
+[[autodoc]] AutoModelForDocumentQuestionAnswering
+
+### TFAutoModelForDocumentQuestionAnswering[[transformers.TFAutoModelForDocumentQuestionAnswering]]
+
+[[autodoc]] TFAutoModelForDocumentQuestionAnswering
+
+### AutoModelForVisualQuestionAnswering[[transformers.AutoModelForVisualQuestionAnswering]]
+
+[[autodoc]] AutoModelForVisualQuestionAnswering
+
+### AutoModelForVision2Seq[[transformers.AutoModelForVision2Seq]]
+
+[[autodoc]] AutoModelForVision2Seq
+
+### TFAutoModelForVision2Seq[[transformers.TFAutoModelForVision2Seq]]
+
+[[autodoc]] TFAutoModelForVision2Seq
+
+### FlaxAutoModelForVision2Seq[[transformers.FlaxAutoModelForVision2Seq]]
+
+[[autodoc]] FlaxAutoModelForVision2Seq
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/autoformer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/autoformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..e8534ac95c327ab65a1ccc8a3c3fa67fab446344
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/autoformer.md
@@ -0,0 +1,50 @@
+
+
+# Autoformer[[autoformer]]
+
+## 개요[[overview]]
+
+The Autoformer 모델은 Haixu Wu, Jiehui Xu, Jianmin Wang, Mingsheng Long가 제안한 [오토포머: 장기 시계열 예측을 위한 자기상관 분해 트랜스포머](https://arxiv.org/abs/2106.13008) 라는 논문에서 소개 되었습니다.
+
+이 모델은 트랜스포머를 심층 분해 아키텍처로 확장하여, 예측 과정에서 추세와 계절성 요소를 점진적으로 분해할 수 있습니다.
+
+해당 논문의 초록입니다:
+
+*예측 시간을 연장하는 것은 극한 기상 조기 경보 및 장기 에너지 소비 계획과 같은 실제 응용 프로그램에 중요한 요구 사항입니다. 본 논문은 시계열의 장기 예측 문제를 연구합니다. 기존의 트랜스포머 기반 모델들은 장거리 종속성을 발견하기 위해 다양한 셀프 어텐션 메커니즘을 채택합니다. 그러나 장기 미래의 복잡한 시간적 패턴으로 인해 모델이 신뢰할 수 있는 종속성을 찾기 어렵습니다. 또한, 트랜스포머는 긴 시계열의 효율성을 위해 점별 셀프 어텐션의 희소 버전을 채택해야 하므로 정보 활용의 병목 현상이 발생합니다. 우리는 트랜스포머를 넘어서 자기상관 메커니즘을 갖춘 새로운 분해 아키텍처인 Autoformer를 설계했습니다. 우리는 시계열 분해의 전처리 관행을 깨고 이를 심층 모델의 기본 내부 블록으로 혁신했습니다. 이 설계는 Autoformer에 복잡한 시계열에 대한 점진적 분해 능력을 부여합니다. 또한, 확률 과정 이론에서 영감을 받아 시계열의 주기성을 기반으로 자기상관 메커니즘을 설계했으며, 이는 하위 시계열 수준에서 종속성 발견과 표현 집계를 수행합니다. 자기상관은 효율성과 정확도 면에서 셀프 어텐션를 능가합니다. 장기 예측에서 Autoformer는 에너지, 교통, 경제, 날씨, 질병 등 5가지 실용적 응용 분야를 포괄하는 6개 벤치마크에서 38%의 상대적 개선으로 최첨단 정확도를 달성했습니다.*
+
+이 모델은 [elisim](https://huggingface.co/elisim)과 [kashif](https://huggingface.co/kashif)에 의해 기여 되었습니다.
+원본 코드는 [이곳](https://github.com/thuml/Autoformer)에서 확인할 수 있습니다.
+
+## 자료[[resources]]
+
+시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+- HuggingFace 블로그에서 Autoformer 포스트를 확인하세요: [네, 그렇습니다, 트랜스포머는 시계열 예측에 효과적입니다(+ Autoformer)](https://huggingface.co/blog/autoformer)
+
+## AutoformerConfig[[transformers.AutoformerConfig]]
+
+[[autodoc]] AutoformerConfig
+
+## AutoformerModel[[transformers.AutoformerModel]]
+
+[[autodoc]] AutoformerModel
+ - forward
+
+## AutoformerForPrediction[[transformers.AutoformerForPrediction]]
+
+[[autodoc]] AutoformerForPrediction
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bart.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bart.md
new file mode 100644
index 0000000000000000000000000000000000000000..0f7636b3cc95c284de5eb5a650b6393c6d0c69bf
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bart.md
@@ -0,0 +1,217 @@
+
+
+# BART[[bart]]
+
+
+
+## 개요 [[overview]]
+
+Bart 모델은 2019년 10월 29일 Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov, Luke Zettlemoyer가 발표한 [BART: 자연어 생성, 번역, 이해를 위한 잡음 제거 seq2seq 사전 훈련](https://arxiv.org/abs/1910.13461)이라는 논문에서 소개되었습니다.
+
+논문의 초록에 따르면,
+
+- Bart는 양방향 인코더(BERT와 유사)와 왼쪽에서 오른쪽으로 디코딩하는 디코더(GPT와 유사)를 사용하는 표준 seq2seq/기계 번역 아키텍처를 사용합니다.
+- 사전 훈련 작업은 원래 문장의 순서를 무작위로 섞고, 텍스트의 일부 구간을 단일 마스크 토큰으로 대체하는 새로운 인필링(in-filling) 방식을 포함합니다.
+- BART는 특히 텍스트 생성을 위한 미세 조정에 효과적이지만 이해 작업에도 잘 작동합니다. GLUE와 SQuAD에서 비슷한 훈련 리소스로 RoBERTa의 성능과 일치하며, 추상적 대화, 질의응답, 요약 작업 등에서 최대 6 ROUGE 점수의 향상을 보이며 새로운 최고 성능을 달성했습니다.
+
+이 모델은 [sshleifer](https://huggingface.co/sshleifer)에 의해 기여 되었습니다. 저자의 코드는 [이곳](https://github.com/pytorch/fairseq/tree/master/examples/bart)에서 확인할 수 있습니다.
+
+## 사용 팁:[[usage-tips]]
+
+- BART는 절대 위치 임베딩을 사용하는 모델이므로 일반적으로 입력을 왼쪽보다는 오른쪽에 패딩하는 것이 좋습니다.
+- 인코더와 디코더가 있는 seq2seq 모델입니다. 인코더에는 손상된 토큰이(corrupted tokens) 입력되고, 디코더에는 원래 토큰이 입력됩니다(단, 일반적인 트랜스포머 디코더처럼 미래 단어를 숨기는 마스크가 있습니다). 사전 훈련 작업에서 인코더에 적용되는 변환들의 구성은 다음과 같습니다:
+
+사전 훈련 작업에서 인코더에 적용되는 변환들의 구성은 다음과 같습니다:
+
+ * 무작위 토큰 마스킹 (BERT 처럼)
+ * 무작위 토큰 삭제
+ * k개 토큰의 범위를 단일 마스크 토큰으로 마스킹 (0개 토큰의 범위는 마스크 토큰의 삽입을 의미)
+ * 문장 순서 뒤섞기
+ * 특정 토큰에서 시작하도록 문서 회전
+
+## 구현 노트[[implementation-notes]]
+
+- Bart는 시퀀스 분류에 `token_type_ids`를 사용하지 않습니다. 적절하게 나누기 위해서 [`BartTokenizer`]나
+ [`~BartTokenizer.encode`]를 사용합니다.
+- [`BartModel`]의 정방향 전달은 `decoder_input_ids`가 전달되지 않으면 `decoder_input_ids`를 자동으로 생성할 것입니다. 이는 다른 일부 모델링 API와 다른 점입니다. 이 기능의 일반적인 사용 사례는 마스크 채우기(mask filling)입니다.
+- 모델 예측은 `forced_bos_token_id=0`일 때 기존 구현과 동일하게 작동하도록 의도되었습니다. 하지만, [`fairseq.encode`]에 전달하는 문자열이 공백으로 시작할 때만 이 기능이 작동합니다.
+- [`~generation.GenerationMixin.generate`]는 요약과 같은 조건부 생성 작업에 사용되어야 합니다. 자세한 내용은 해당 문서의 예제를 참조하세요.
+- *facebook/bart-large-cnn* 가중치를 로드하는 모델은 `mask_token_id`가 없거나, 마스크 채우기 작업을 수행할 수 없습니다.
+
+## 마스크 채우기[[mask-filling]]
+
+`facebook/bart-base`와 `facebook/bart-large` 체크포인트는 멀티 토큰 마스크를 채우는데 사용될 수 있습니다.
+
+```python
+from transformers import BartForConditionalGeneration, BartTokenizer
+
+model = BartForConditionalGeneration.from_pretrained("facebook/bart-large", forced_bos_token_id=0)
+tok = BartTokenizer.from_pretrained("facebook/bart-large")
+example_english_phrase = "UN Chief Says There Is No in Syria"
+batch = tok(example_english_phrase, return_tensors="pt")
+generated_ids = model.generate(batch["input_ids"])
+assert tok.batch_decode(generated_ids, skip_special_tokens=True) == [
+ "UN Chief Says There Is No Plan to Stop Chemical Weapons in Syria"
+]
+```
+
+## 자료[[resources]]
+
+BART를 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+
+
+
+## BartModel[[transformers.BartModel]]
+
+[[autodoc]] BartModel
+ - forward
+
+## BartForConditionalGeneration[[transformers.BartForConditionalGeneration]]
+
+[[autodoc]] BartForConditionalGeneration
+ - forward
+
+## BartForSequenceClassification[[transformers.BartForSequenceClassification]]
+
+[[autodoc]] BartForSequenceClassification
+ - forward
+
+## BartForQuestionAnswering[[transformers.BartForQuestionAnswering]]
+
+[[autodoc]] BartForQuestionAnswering
+ - forward
+
+## BartForCausalLM[[transformers.BartForCausalLM]]
+
+[[autodoc]] BartForCausalLM
+ - forward
+
+
+
+
+## TFBartModel[[transformers.TFBartModel]]
+
+[[autodoc]] TFBartModel
+ - call
+
+## TFBartForConditionalGeneration[[transformers.TFBartForConditionalGeneration]]
+
+[[autodoc]] TFBartForConditionalGeneration
+ - call
+
+## TFBartForSequenceClassification[[transformers.TFBartForSequenceClassification]]
+
+[[autodoc]] TFBartForSequenceClassification
+ - call
+
+
+
+
+## FlaxBartModel[[transformers.FlaxBartModel]]
+
+[[autodoc]] FlaxBartModel
+ - __call__
+ - encode
+ - decode
+
+## FlaxBartForConditionalGeneration[[transformers.FlaxBartForConditionalGeneration]]
+
+[[autodoc]] FlaxBartForConditionalGeneration
+ - __call__
+ - encode
+ - decode
+
+## FlaxBartForSequenceClassification[[transformers.FlaxBartForSequenceClassification]]
+
+[[autodoc]] FlaxBartForSequenceClassification
+ - __call__
+ - encode
+ - decode
+
+## FlaxBartForQuestionAnswering[[transformers.FlaxBartForQuestionAnswering]]
+
+[[autodoc]] FlaxBartForQuestionAnswering
+ - __call__
+ - encode
+ - decode
+
+## FlaxBartForCausalLM[[transformers.FlaxBartForCausalLM]]
+
+[[autodoc]] FlaxBartForCausalLM
+ - __call__
+
+
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/barthez.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/barthez.md
new file mode 100644
index 0000000000000000000000000000000000000000..131db38856cc1b253a6cbdaa6e3d45de9197de1c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/barthez.md
@@ -0,0 +1,60 @@
+
+
+# BARThez [[barthez]]
+
+## 개요 [[overview]]
+
+BARThez 모델은 2020년 10월 23일, Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis에 의해 [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321)에서 제안되었습니다.
+
+이 논문의 초록:
+
+
+*자기지도 학습에 의해 가능해진 귀납적 전이 학습은 자연어 처리(NLP) 분야 전반에 걸쳐 큰 반향을 일으켰으며,
+BERT와 BART와 같은 모델들은 수많은 자연어 이해 작업에서 새로운 최첨단 성과를 기록했습니다. 일부 주목할 만한 예외가 있지만,
+대부분의 사용 가능한 모델과 연구는 영어에 집중되어 있었습니다. 본 연구에서는 BARThez를 소개합니다.
+이는 (우리가 아는 한) 프랑스어를 위한 첫 번째 BART 모델입니다.
+BARThez는 과거 연구에서 얻은 매우 큰 프랑스어 단일 언어 말뭉치로 사전훈련되었으며,
+BART의 변형 방식에 맞게 조정되었습니다.
+CamemBERT 및 FlauBERT와 같은 기존의 BERT 기반 프랑스어 모델과 달리, BARThez는 생성 작업에 특히 적합합니다.
+이는 인코더뿐만 아니라 디코더도 사전훈련되었기 때문입니다.
+우리는 FLUE 벤치마크에서의 판별 작업 외에도 이 논문과 함께 공개하는 새로운 요약 데이터셋인 OrangeSum에서 BARThez를 평가했습니다.
+또한 이미 사전훈련된 다국어 BART의 사전훈련을 BARThez의 말뭉치로 계속 진행하였으며,
+결과적으로 얻어진 모델인 mBARTHez가 기본 BARThez보다 유의미한 성능 향상을 보였고,
+CamemBERT 및 FlauBERT와 동등하거나 이를 능가함을 보였습니다.*
+
+이 모델은 [moussakam](https://huggingface.co/moussakam)이 기여했습니다. 저자의 코드는 [여기](https://github.com/moussaKam/BARThez)에서 찾을 수 있습니다.
+
+
+
+BARThez 구현은 🤗 BART와 동일하나, 토큰화에서 차이가 있습니다. 구성 클래스와 그 매개변수에 대한 정보는 [BART 문서](bart)를 참조하십시오.
+BARThez 전용 토크나이저는 아래에 문서화되어 있습니다.
+
+
+
+## 리소스 [[resources]]
+
+- BARThez는 🤗 BART와 유사한 방식으로 시퀀스-투-시퀀스 작업에 맞춰 미세 조정될 수 있습니다. 다음을 확인하세요:
+ [examples/pytorch/summarization/](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization/README.md).
+
+
+## BarthezTokenizer [[bartheztokenizer]]
+
+[[autodoc]] BarthezTokenizer
+
+## BarthezTokenizerFast [[bartheztokenizerfast]]
+
+[[autodoc]] BarthezTokenizerFast
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bartpho.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bartpho.md
new file mode 100644
index 0000000000000000000000000000000000000000..a323c28152c5d9969cee4b08b9dd21a8cb9ab999
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bartpho.md
@@ -0,0 +1,86 @@
+
+
+# BARTpho [[bartpho]]
+
+## 개요 [[overview]]
+
+BARTpho 모델은 Nguyen Luong Tran, Duong Minh Le, Dat Quoc Nguyen에 의해 [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701)에서 제안되었습니다.
+
+이 논문의 초록은 다음과 같습니다:
+
+*우리는 BARTpho_word와 BARTpho_syllable의 두 가지 버전으로 BARTpho를 제시합니다.
+이는 베트남어를 위해 사전훈련된 최초의 대규모 단일 언어 시퀀스-투-시퀀스 모델입니다.
+우리의 BARTpho는 시퀀스-투-시퀀스 디노이징 모델인 BART의 "large" 아키텍처와 사전훈련 방식을 사용하여, 생성형 NLP 작업에 특히 적합합니다.
+베트남어 텍스트 요약의 다운스트림 작업 실험에서,
+자동 및 인간 평가 모두에서 BARTpho가 강력한 기준인 mBART를 능가하고 최신 성능을 개선했음을 보여줍니다.
+우리는 향후 연구 및 베트남어 생성형 NLP 작업의 응용을 촉진하기 위해 BARTpho를 공개합니다.*
+
+이 모델은 [dqnguyen](https://huggingface.co/dqnguyen)이 기여했습니다. 원본 코드는 [여기](https://github.com/VinAIResearch/BARTpho)에서 찾을 수 있습니다.
+
+## 사용 예시 [[usage-example]]
+
+```python
+>>> import torch
+>>> from transformers import AutoModel, AutoTokenizer
+
+>>> bartpho = AutoModel.from_pretrained("vinai/bartpho-syllable")
+
+>>> tokenizer = AutoTokenizer.from_pretrained("vinai/bartpho-syllable")
+
+>>> line = "Chúng tôi là những nghiên cứu viên."
+
+>>> input_ids = tokenizer(line, return_tensors="pt")
+
+>>> with torch.no_grad():
+... features = bartpho(**input_ids) # 이제 모델 출력은 튜플입니다
+
+>>> # With TensorFlow 2.0+:
+>>> from transformers import TFAutoModel
+
+>>> bartpho = TFAutoModel.from_pretrained("vinai/bartpho-syllable")
+>>> input_ids = tokenizer(line, return_tensors="tf")
+>>> features = bartpho(**input_ids)
+```
+
+## 사용 팁 [[usage-tips]]
+
+- mBART를 따르며, BARTpho는 BART의 "large" 아키텍처에 인코더와 디코더의 상단에 추가적인 레이어 정규화 레이어를 사용합니다.
+따라서 [BART 문서](bart)에 있는 사용 예시를 BARTpho에 맞게 적용하려면
+BART 전용 클래스를 mBART 전용 클래스로 대체하여 조정해야 합니다.
+예를 들어:
+
+```python
+>>> from transformers import MBartForConditionalGeneration
+
+>>> bartpho = MBartForConditionalGeneration.from_pretrained("vinai/bartpho-syllable")
+>>> TXT = "Chúng tôi là nghiên cứu viên."
+>>> input_ids = tokenizer([TXT], return_tensors="pt")["input_ids"]
+>>> logits = bartpho(input_ids).logits
+>>> masked_index = (input_ids[0] == tokenizer.mask_token_id).nonzero().item()
+>>> probs = logits[0, masked_index].softmax(dim=0)
+>>> values, predictions = probs.topk(5)
+>>> print(tokenizer.decode(predictions).split())
+```
+
+- 이 구현은 토큰화만을 위한 것입니다: "monolingual_vocab_file"은 다국어
+ XLM-RoBERTa에서 제공되는 사전훈련된 SentencePiece 모델
+ "vocab_file"에서 추출된 베트남어 전용 유형으로 구성됩니다.
+ 다른 언어들도 이 사전훈련된 다국어 SentencePiece 모델 "vocab_file"을 하위 단어 분할에 사용하면, 자신의 언어 전용 "monolingual_vocab_file"과 함께 BartphoTokenizer를 재사용할 수 있습니다.
+
+## BartphoTokenizer [[bartphotokenizer]]
+
+[[autodoc]] BartphoTokenizer
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bert-japanese.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bert-japanese.md
new file mode 100644
index 0000000000000000000000000000000000000000..8c21ef3558908e76288f670cf57d97252775252f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bert-japanese.md
@@ -0,0 +1,79 @@
+
+
+# 일본어 BERT (BertJapanese) [[bertjapanese]]
+
+## 개요 [[overview]]
+
+일본어 문장에 학습된 BERT 모델 입니다.
+
+각각 서로 다른 토큰화 방법을 사용하는 두 모델:
+
+- MeCab와 WordPiece를 사용하여 토큰화합니다. 이를 위해 추가 의존성 [fugashi](https://github.com/polm/fugashi)이 필요합니다. (이는 [MeCab](https://taku910.github.io/mecab/)의 래퍼입니다.)
+- 문자 단위로 토큰화합니다.
+
+*MecabTokenizer*를 사용하려면, 의존성을 설치하기 위해 `pip install transformers["ja"]` (또는 소스에서 설치하는 경우 `pip install -e .["ja"]`) 명령을 실행해야 합니다.
+
+자세한 내용은 [cl-tohoku 리포지토리](https://github.com/cl-tohoku/bert-japanese)에서 확인하세요.
+
+MeCab과 WordPiece 토큰화를 사용하는 모델 예시:
+
+```python
+>>> import torch
+>>> from transformers import AutoModel, AutoTokenizer
+
+>>> bertjapanese = AutoModel.from_pretrained("cl-tohoku/bert-base-japanese")
+>>> tokenizer = AutoTokenizer.from_pretrained("cl-tohoku/bert-base-japanese")
+
+>>> ## Input Japanese Text
+>>> line = "吾輩は猫である。"
+
+>>> inputs = tokenizer(line, return_tensors="pt")
+
+>>> print(tokenizer.decode(inputs["input_ids"][0]))
+[CLS] 吾輩 は 猫 で ある 。 [SEP]
+
+>>> outputs = bertjapanese(**inputs)
+```
+
+문자 토큰화를 사용하는 모델 예시:
+
+```python
+>>> bertjapanese = AutoModel.from_pretrained("cl-tohoku/bert-base-japanese-char")
+>>> tokenizer = AutoTokenizer.from_pretrained("cl-tohoku/bert-base-japanese-char")
+
+>>> ## Input Japanese Text
+>>> line = "吾輩は猫である。"
+
+>>> inputs = tokenizer(line, return_tensors="pt")
+
+>>> print(tokenizer.decode(inputs["input_ids"][0]))
+[CLS] 吾 輩 は 猫 で あ る 。 [SEP]
+
+>>> outputs = bertjapanese(**inputs)
+```
+
+
+
+이는 토큰화 방법을 제외하고는 BERT와 동일합니다. API 참조 정보는 [BERT 문서](https://huggingface.co/docs/transformers/main/en/model_doc/bert)를 참조하세요.
+이 모델은 [cl-tohoku](https://huggingface.co/cl-tohoku)께서 기여하였습니다.
+
+
+
+
+## BertJapaneseTokenizer
+
+[[autodoc]] BertJapaneseTokenizer
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bert.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bert.md
new file mode 100644
index 0000000000000000000000000000000000000000..531d3e3dd6394766531b64adacf280d6392576c4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bert.md
@@ -0,0 +1,340 @@
+
+
+# BERT[[BERT]]
+
+
+
+## 개요[[Overview]]
+
+BERT 모델은 Jacob Devlin. Ming-Wei Chang, Kenton Lee, Kristina Touranova가 제안한 논문 [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805)에서 소개되었습니다. BERT는 사전 학습된 양방향 트랜스포머로, Toronto Book Corpus와 Wikipedia로 구성된 대규모 코퍼스에서 마스킹된 언어 모델링과 다음 문장 예측(Next Sentence Prediction) 목표를 결합해 학습되었습니다.
+
+해당 논문의 초록입니다:
+
+*우리는 BERT(Bidirectional Encoder Representations from Transformers)라는 새로운 언어 표현 모델을 소개합니다. 최근의 다른 언어 표현 모델들과 달리, BERT는 모든 계층에서 양방향으로 양쪽 문맥을 조건으로 사용하여 비지도 학습된 텍스트에서 깊이 있는 양방향 표현을 사전 학습하도록 설계되었습니다. 그 결과, 사전 학습된 BERT 모델은 추가적인 출력 계층 하나만으로 질문 응답, 언어 추론과 같은 다양한 작업에서 미세 조정될 수 있으므로, 특정 작업을 위해 아키텍처를 수정할 필요가 없습니다.*
+
+*BERT는 개념적으로 단순하면서도 실증적으로 강력한 모델입니다. BERT는 11개의 자연어 처리 과제에서 새로운 최고 성능을 달성했으며, GLUE 점수를 80.5% (7.7% 포인트 절대 개선)로, MultiNLI 정확도를 86.7% (4.6% 포인트 절대 개선), SQuAD v1.1 질문 응답 테스트에서 F1 점수를 93.2 (1.5% 포인트 절대 개선)로, SQuAD v2.0에서 F1 점수를 83.1 (5.1% 포인트 절대 개선)로 향상시켰습니다.*
+
+이 모델은 [thomwolf](https://huggingface.co/thomwolf)가 기여하였습니다. 원본 코드는 [여기](https://github.com/google-research/bert)에서 확인할 수 있습니다.
+
+## 사용 팁[[Usage tips]]
+
+- BERT는 절대 위치 임베딩을 사용하는 모델이므로 입력을 왼쪽이 아니라 오른쪽에서 패딩하는 것이 일반적으로 권장됩니다.
+- BERT는 마스킹된 언어 모델(MLM)과 Next Sentence Prediction(NSP) 목표로 학습되었습니다. 이는 마스킹된 토큰 예측과 전반적인 자연어 이해(NLU)에 뛰어나지만, 텍스트 생성에는 최적화되어있지 않습니다.
+- BERT의 사전 학습 과정에서는 입력 데이터를 무작위로 마스킹하여 일부 토큰을 마스킹합니다. 전체 토큰 중 약 15%가 다음과 같은 방식으로 마스킹됩니다:
+
+ * 80% 확률로 마스크 토큰으로 대체
+ * 10% 확률로 임의의 다른 토큰으로 대체
+ * 10% 확률로 원래 토큰 그대로 유지
+
+- 모델의 주요 목표는 원본 문장을 예측하는 것이지만, 두 번째 목표가 있습니다: 입력으로 문장 A와 B (사이에는 구분 토큰이 있음)가 주어집니다. 이 문장 쌍이 연속될 확률은 50%이며, 나머지 50%는 서로 무관한 문장들입니다. 모델은 이 두 문장이 아닌지를 예측해야 합니다.
+
+### Scaled Dot Product Attention(SDPA) 사용하기 [[Using Scaled Dot Product Attention (SDPA)]]
+
+Pytorch는 `torch.nn.functional`의 일부로 Scaled Dot Product Attention(SDPA) 연산자를 기본적으로 제공합니다. 이 함수는 입력과 하드웨어에 따라 여러 구현 방식을 사용할 수 있습니다. 자세한 내용은 [공식 문서](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)나 [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)에서 확인할 수 있습니다.
+
+`torch>=2.1.1`에서는 구현이 가능한 경우 SDPA가 기본적으로 사용되지만, `from_pretrained()`함수에서 `attn_implementation="sdpa"`를 설정하여 SDPA를 명시적으로 사용하도록 지정할 수도 있습니다.
+
+```
+from transformers import BertModel
+
+model = BertModel.from_pretrained("bert-base-uncased", torch_dtype=torch.float16, attn_implementation="sdpa")
+...
+```
+
+최적 성능 향상을 위해 모델을 반정밀도(예: `torch.float16` 또는 `torch.bfloat16`)로 불러오는 것을 권장합니다.
+
+로컬 벤치마크 (A100-80GB, CPUx12, RAM 96.6GB, PyTorch 2.2.0, OS Ubuntu 22.04)에서 `float16`을 사용해 학습 및 추론을 수행한 결과, 다음과 같은 속도 향상이 관찰되었습니다.
+
+#### 학습 [[Training]]
+
+|batch_size|seq_len|Time per batch (eager - s)|Time per batch (sdpa - s)|Speedup (%)|Eager peak mem (MB)|sdpa peak mem (MB)|Mem saving (%)|
+|----------|-------|--------------------------|-------------------------|-----------|-------------------|------------------|--------------|
+|4 |256 |0.023 |0.017 |35.472 |939.213 |764.834 |22.800 |
+|4 |512 |0.023 |0.018 |23.687 |1970.447 |1227.162 |60.569 |
+|8 |256 |0.023 |0.018 |23.491 |1594.295 |1226.114 |30.028 |
+|8 |512 |0.035 |0.025 |43.058 |3629.401 |2134.262 |70.054 |
+|16 |256 |0.030 |0.024 |25.583 |2874.426 |2134.262 |34.680 |
+|16 |512 |0.064 |0.044 |46.223 |6964.659 |3961.013 |75.830 |
+
+#### 추론 [[Inference]]
+
+|batch_size|seq_len|Per token latency eager (ms)|Per token latency SDPA (ms)|Speedup (%)|Mem eager (MB)|Mem BT (MB)|Mem saved (%)|
+|----------|-------|----------------------------|---------------------------|-----------|--------------|-----------|-------------|
+|1 |128 |5.736 |4.987 |15.022 |282.661 |282.924 |-0.093 |
+|1 |256 |5.689 |4.945 |15.055 |298.686 |298.948 |-0.088 |
+|2 |128 |6.154 |4.982 |23.521 |314.523 |314.785 |-0.083 |
+|2 |256 |6.201 |4.949 |25.303 |347.546 |347.033 |0.148 |
+|4 |128 |6.049 |4.987 |21.305 |378.895 |379.301 |-0.107 |
+|4 |256 |6.285 |5.364 |17.166 |443.209 |444.382 |-0.264 |
+
+
+
+## 자료[[Resources]]
+
+BERT를 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+
+
+
+## BertTokenizerFast
+
+[[autodoc]] BertTokenizerFast
+
+
+
+
+## TFBertTokenizer
+
+[[autodoc]] TFBertTokenizer
+
+
+
+
+## Bert specific outputs
+
+[[autodoc]] models.bert.modeling_bert.BertForPreTrainingOutput
+
+[[autodoc]] models.bert.modeling_tf_bert.TFBertForPreTrainingOutput
+
+[[autodoc]] models.bert.modeling_flax_bert.FlaxBertForPreTrainingOutput
+
+
+
+
+
+## BertModel
+
+[[autodoc]] BertModel
+ - forward
+
+## BertForPreTraining
+
+[[autodoc]] BertForPreTraining
+ - forward
+
+## BertLMHeadModel
+
+[[autodoc]] BertLMHeadModel
+ - forward
+
+## BertForMaskedLM
+
+[[autodoc]] BertForMaskedLM
+ - forward
+
+## BertForNextSentencePrediction
+
+[[autodoc]] BertForNextSentencePrediction
+ - forward
+
+## BertForSequenceClassification
+
+[[autodoc]] BertForSequenceClassification
+ - forward
+
+## BertForMultipleChoice
+
+[[autodoc]] BertForMultipleChoice
+ - forward
+
+## BertForTokenClassification
+
+[[autodoc]] BertForTokenClassification
+ - forward
+
+## BertForQuestionAnswering
+
+[[autodoc]] BertForQuestionAnswering
+ - forward
+
+
+
+
+## TFBertModel
+
+[[autodoc]] TFBertModel
+ - call
+
+## TFBertForPreTraining
+
+[[autodoc]] TFBertForPreTraining
+ - call
+
+## TFBertModelLMHeadModel
+
+[[autodoc]] TFBertLMHeadModel
+ - call
+
+## TFBertForMaskedLM
+
+[[autodoc]] TFBertForMaskedLM
+ - call
+
+## TFBertForNextSentencePrediction
+
+[[autodoc]] TFBertForNextSentencePrediction
+ - call
+
+## TFBertForSequenceClassification
+
+[[autodoc]] TFBertForSequenceClassification
+ - call
+
+## TFBertForMultipleChoice
+
+[[autodoc]] TFBertForMultipleChoice
+ - call
+
+## TFBertForTokenClassification
+
+[[autodoc]] TFBertForTokenClassification
+ - call
+
+## TFBertForQuestionAnswering
+
+[[autodoc]] TFBertForQuestionAnswering
+ - call
+
+
+
+
+## FlaxBertModel
+
+[[autodoc]] FlaxBertModel
+ - __call__
+
+## FlaxBertForPreTraining
+
+[[autodoc]] FlaxBertForPreTraining
+ - __call__
+
+## FlaxBertForCausalLM
+
+[[autodoc]] FlaxBertForCausalLM
+ - __call__
+
+## FlaxBertForMaskedLM
+
+[[autodoc]] FlaxBertForMaskedLM
+ - __call__
+
+## FlaxBertForNextSentencePrediction
+
+[[autodoc]] FlaxBertForNextSentencePrediction
+ - __call__
+
+## FlaxBertForSequenceClassification
+
+[[autodoc]] FlaxBertForSequenceClassification
+ - __call__
+
+## FlaxBertForMultipleChoice
+
+[[autodoc]] FlaxBertForMultipleChoice
+ - __call__
+
+## FlaxBertForTokenClassification
+
+[[autodoc]] FlaxBertForTokenClassification
+ - __call__
+
+## FlaxBertForQuestionAnswering
+
+[[autodoc]] FlaxBertForQuestionAnswering
+ - __call__
+
+
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bertweet.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bertweet.md
new file mode 100644
index 0000000000000000000000000000000000000000..7a46087d0a8ebf85929aadbb74808ffe029537c9
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/bertweet.md
@@ -0,0 +1,67 @@
+
+
+# BERTweet [[bertweet]]
+
+## 개요 [[overview]]
+
+BERTweet 모델은 Dat Quoc Nguyen, Thanh Vu, Anh Tuan Nguyen에 의해 [BERTweet: A pre-trained language model for English Tweets](https://www.aclweb.org/anthology/2020.emnlp-demos.2.pdf) 에서 제안되었습니다.
+
+해당 논문의 초록 :
+
+*영어 트윗을 위한 최초의 공개 대규모 사전 학습된 언어 모델인 BERTweet을 소개합니다.
+BERTweet은 BERT-base(Devlin et al., 2019)와 동일한 아키텍처를 가지고 있으며, RoBERTa 사전 학습 절차(Liu et al., 2019)를 사용하여 학습되었습니다.
+실험 결과, BERTweet은 강력한 기준 모델인 RoBERTa-base 및 XLM-R-base(Conneau et al., 2020)의 성능을 능가하여 세 가지 트윗 NLP 작업(품사 태깅, 개체명 인식, 텍스트 분류)에서 이전 최신 모델보다 더 나은 성능을 보여주었습니다.*
+
+이 모델은 [dqnguyen](https://huggingface.co/dqnguyen) 께서 기여하셨습니다. 원본 코드는 [여기](https://github.com/VinAIResearch/BERTweet).에서 확인할 수 있습니다.
+
+
+## 사용 예시 [[usage-example]]
+
+```python
+>>> import torch
+>>> from transformers import AutoModel, AutoTokenizer
+
+>>> bertweet = AutoModel.from_pretrained("vinai/bertweet-base")
+
+>>> # 트랜스포머 버전 4.x 이상 :
+>>> tokenizer = AutoTokenizer.from_pretrained("vinai/bertweet-base", use_fast=False)
+
+>>> # 트랜스포머 버전 3.x 이상:
+>>> # tokenizer = AutoTokenizer.from_pretrained("vinai/bertweet-base")
+
+>>> # 입력된 트윗은 이미 정규화되었습니다!
+>>> line = "SC has first two presumptive cases of coronavirus , DHEC confirms HTTPURL via @USER :cry:"
+
+>>> input_ids = torch.tensor([tokenizer.encode(line)])
+
+>>> with torch.no_grad():
+... features = bertweet(input_ids) # Models outputs are now tuples
+
+>>> # With TensorFlow 2.0+:
+>>> # from transformers import TFAutoModel
+>>> # bertweet = TFAutoModel.from_pretrained("vinai/bertweet-base")
+```
+
+
+
+이 구현은 토큰화 방법을 제외하고는 BERT와 동일합니다. API 참조 정보는 [BERT 문서](bert) 를 참조하세요.
+
+
+
+## Bertweet 토큰화(BertweetTokenizer) [[transformers.BertweetTokenizer]]
+
+[[autodoc]] BertweetTokenizer
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/biogpt.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/biogpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..4b24af8493b9d5dc025416476cb75876c91e5249
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/biogpt.md
@@ -0,0 +1,109 @@
+
+
+# BioGPT [[biogpt]]
+
+## 개요 [[overview]]
+
+BioGPT는 Renqian Luo, Liai Sun, Yingce Xia, Tao Qin, Sheng Zhang, Hoifung Poon, Tie-Yan Liu에 의해 [BioGPT: generative pre-trained transformer for biomedical text generation and mining](https://academic.oup.com/bib/advance-article/doi/10.1093/bib/bbac409/6713511?guestAccessKey=a66d9b5d-4f83-4017-bb52-405815c907b9) 에서 제안된 모델입니다. BioGPT는 생물의학 텍스트 생성과 마이닝을 위해 도메인에 특화된 생성형 사전 학습 트랜스포머 언어 모델입니다. BioGPT는 트랜스포머 언어 모델 구조를 따르며, 1,500만 개의 PubMed 초록을 이용해 처음부터 학습되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*생물의학 분야에서 사전 학습된 언어 모델은 일반 자연어 처리 분야에서의 성공에 영감을 받아 점점 더 많은 주목을 받고 있습니다. 일반 언어 분야에서 사전 학습된 언어 모델의 두 가지 주요 계통인 BERT(및 그 변형)와 GPT(및 그 변형) 중 첫 번째는 생물의학 분야에서 BioBERT와 PubMedBERT와 같이 광범위하게 연구되었습니다. 이들은 다양한 분류 기반의 생물의학 작업에서 큰 성공을 거두었지만, 생성 능력의 부족은 그들의 적용 범위를 제한했습니다. 본 논문에서는 대규모 생물의학 문헌을 사전 학습한 도메인 특화 생성형 트랜스포머 언어 모델인 BioGPT를 제안합니다. 우리는 6개의 생물의학 자연어 처리 작업에서 BioGPT를 평가한 결과, 대부분의 작업에서 이전 모델보다 우수한 성능을 보였습니다. 특히, BC5CDR, KD-DTI, DDI 엔드-투-엔드 관계 추출 작업에서 각각 44.98%, 38.42%, 40.76%의 F1 점수를 기록하였으며, PubMedQA에서 78.2%의 정확도를 달성해 새로운 기록을 세웠습니다. 또한 텍스트 생성에 대한 사례 연구는 생물의학 용어에 대한 유창한 설명을 생성하는 데 있어 BioGPT의 장점을 더욱 입증했습니다.*
+
+이 모델은 [kamalkraj](https://huggingface.co/kamalkraj)에 의해 기여되었습니다. 원본 코드는 [여기](https://github.com/microsoft/BioGPT)에서 찾을 수 있습니다.
+
+## 사용 팁 [[usage-tips]]
+
+- BioGPT는 절대적 위치 임베딩(absolute position embedding)을 사용하므로, 입력을 왼쪽이 아닌 오른쪽에서 패딩하는 것이 권장됩니다.
+- BioGPT는 인과적 언어 모델링(Casual Langague Modeling, CLM) 목표로 학습되었기 때문에, 다음 토큰을 예측하는 데 강력한 성능을 보입니다. 이 기능을 활용하여 BioGPT는 구문적으로 일관된 텍스트를 생성할 수 있으며, 예시 스크립트 `run_generation.py`에서 이를 확인할 수 있습니다.
+- 이 모델은 `past_key_values`(PyTorch 용)를 입력으로 받을 수 있는데, 이는 이전에 계산된 키/값 어텐션 쌍입니다. 이 값을 사용하면 텍스트 생성 중 이미 계산된 값을 다시 계산하지 않도록 할 수 있습니다. PyTorch에서 `past_key_values` 인수는 BioGptForCausalLM.forward() 메소드에서 자세히 설명되어 있습니다.
+
+### Scaled Dot Product Attention(SDPA) 사용 [[using-scaled-dot-product-attention-sdpa]]
+
+PyTorch는 `torch.nn.functional`의 일부로 스케일된 점곱 어텐션(SDPA) 연산자를 기본적으로 포함합니다. 이 함수는 입력과 사용 중인 하드웨어에 따라 여러 구현을 적용할 수 있습니다. 자세한 내용은 [공식 문서](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html) 또는 [GPU 추론](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention) 페이지를 참조하세요.
+
+`torch>=2.1.1`에서 구현이 가능한 경우 SDPA는 기본적으로 사용되며, `attn_implementation="sdpa"`를 `from_pretrained()`에서 설정하여 SDPA 사용을 명시적으로 요청할 수 있습니다.
+
+```
+from transformers import BioGptForCausalLM
+model = BioGptForCausalLM.from_pretrained("microsoft/biogpt", attn_implementation="sdpa", torch_dtype=torch.float16)
+```
+
+NVIDIA GeForce RTX 2060-8GB, PyTorch 2.3.1, Ubuntu 20.04 환경에서 `float16` 및 CausalLM 헤드가 있는 `microsoft/biogpt` 모델로 로컬 벤치마크를 수행한 결과, 훈련 중 다음과 같은 속도 향상을 확인했습니다.
+
+최적의 속도 향상을 위해 모델을 반정밀도(예: `torch.float16` 또는 `torch.bfloat16`)로 로드하는 것이 좋습니다.
+
+| num_training_steps | batch_size | seq_len | is cuda | Time per batch (eager - s) | Time per batch (sdpa - s) | Speedup (%) | Eager peak mem (MB) | sdpa peak mem (MB) | Mem saving (%) |
+|--------------------|------------|---------|---------|----------------------------|---------------------------|-------------|---------------------|--------------------|----------------|
+| 100 | 1 | 128 | False | 0.038 | 0.031 | 21.301 | 1601.862 | 1601.497 | 0.023 |
+| 100 | 1 | 256 | False | 0.039 | 0.034 | 15.084 | 1624.944 | 1625.296 | -0.022 |
+| 100 | 2 | 128 | False | 0.039 | 0.033 | 16.820 | 1624.567 | 1625.296 | -0.045 |
+| 100 | 2 | 256 | False | 0.065 | 0.059 | 10.255 | 1672.164 | 1672.164 | 0.000 |
+| 100 | 4 | 128 | False | 0.062 | 0.058 | 6.998 | 1671.435 | 1672.164 | -0.044 |
+| 100 | 4 | 256 | False | 0.113 | 0.100 | 13.316 | 2350.179 | 1848.435 | 27.144 |
+| 100 | 8 | 128 | False | 0.107 | 0.098 | 9.883 | 2098.521 | 1848.435 | 13.530 |
+| 100 | 8 | 256 | False | 0.222 | 0.196 | 13.413 | 3989.980 | 2986.492 | 33.601 |
+
+NVIDIA GeForce RTX 2060-8GB, PyTorch 2.3.1, Ubuntu 20.04 환경에서 `float16` 및 AutoModel 헤드가 있는 `microsoft/biogpt` 모델로 추론 중 다음과 같은 속도 향상을 확인했습니다.
+
+| num_batches | batch_size | seq_len | is cuda | is half | use mask | Per token latency eager (ms) | Per token latency SDPA (ms) | Speedup (%) | Mem eager (MB) | Mem BT (MB) | Mem saved (%) |
+|-------------|------------|---------|---------|---------|----------|------------------------------|-----------------------------|-------------|----------------|--------------|---------------|
+| 50 | 1 | 64 | True | True | True | 0.115 | 0.098 | 17.392 | 716.998 | 716.998 | 0.000 |
+| 50 | 1 | 128 | True | True | True | 0.115 | 0.093 | 24.640 | 730.916 | 730.916 | 0.000 |
+| 50 | 2 | 64 | True | True | True | 0.114 | 0.096 | 19.204 | 730.900 | 730.900 | 0.000 |
+| 50 | 2 | 128 | True | True | True | 0.117 | 0.095 | 23.529 | 759.262 | 759.262 | 0.000 |
+| 50 | 4 | 64 | True | True | True | 0.113 | 0.096 | 18.325 | 759.229 | 759.229 | 0.000 |
+| 50 | 4 | 128 | True | True | True | 0.186 | 0.178 | 4.289 | 816.478 | 816.478 | 0.000 |
+
+
+## 리소스 [[resources]]
+
+- [인과적 언어 모델링 작업 가이드](../tasks/language_modeling)
+
+## BioGptConfig [[transformers.BioGptConfig]]
+
+[[autodoc]] BioGptConfig
+
+
+## BioGptTokenizer [[transformers.BioGptTokenizer]]
+
+[[autodoc]] BioGptTokenizer
+ - save_vocabulary
+
+
+## BioGptModel [[transformers.BioGptModel]]
+
+[[autodoc]] BioGptModel
+ - forward
+
+
+## BioGptForCausalLM [[transformers.BioGptForCausalLM]]
+
+[[autodoc]] BioGptForCausalLM
+ - forward
+
+
+## BioGptForTokenClassification [[transformers.BioGptForTokenClassification]]
+
+[[autodoc]] BioGptForTokenClassification
+ - forward
+
+
+## BioGptForSequenceClassification [[transformers.BioGptForSequenceClassification]]
+
+[[autodoc]] BioGptForSequenceClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/blip-2.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/blip-2.md
new file mode 100644
index 0000000000000000000000000000000000000000..ae3da11d3a18c310568f2b3360f5e8079c48a02c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/blip-2.md
@@ -0,0 +1,98 @@
+
+
+# BLIP-2[[blip-2]]
+
+## 개요[[overview]]
+BLIP-2 모델은 Junnan Li, Dongxu Li, Silvio Savarese, Steven Hoi의 [BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arxiv.org/abs/2301.12597) 논문에서 제안되었습니다. BLIP-2는 동결된 사전 학습 이미지 인코더와 대규모 언어 모델(LLM)을 연결하는 12층의 경량 Transformer 인코더를 학습시켜, 여러 비전-언어 작업에서 SOTA(현재 최고의 성능)을 달성했습니다. 특히, BLIP-2는 800억 개의 파라미터를 가진 Flamingo 모델보다 제로샷 VQAv2에서 8.7% 더 높은 성능을 기록했으며, 학습 가능한 파라미터 수는 Flamingo보다 54배 적습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*비전-언어 사전 학습의 비용은 대규모 모델의 엔드-투-엔드 학습으로 인해 점점 더 부담스러워지고 있습니다. 본 논문은 사전 학습된 이미지 인코더와 대규모 언어 모델을 활용하여 비전-언어 사전 학습을 부트스트래핑하는 일반적이고 효율적인 사전 학습 전략인 BLIP-2를 제안합니다. BLIP-2는 경량화된 Querying Transformer를 통해 모달리티 간의 차이를 연결하며, 두 단계로 사전 학습됩니다. 첫 번째 단계는 동결된 이미지 인코더로부터 비전-언어 표현 학습을 부트스트래핑하고, 두 번째 단계는 동결된 언어 모델로부터 비전-언어 생성 학습을 부트스트래핑합니다. BLIP-2는 기존 방법들에 비해 훨씬 적은 학습 가능한 파라미터로 다양한 비전-언어 작업에서 최첨단 성능을 달성합니다. 예를 들어, 우리 모델은 제로샷 VQAv2에서 Flamingo80B보다 8.7% 높은 성능을 기록하며, 학습 가능한 파라미터 수는 54배 적습니다. 우리는 또한 자연어 명령을 따를 수 있는 제로샷 이미지-텍스트 생성의 새로운 기능을 입증했습니다.*
+
+ BLIP-2 구조. 원본 논문 에서 발췌.
+
+이 모델은 [nielsr](https://huggingface.co/nielsr)가 기여했습니다. 원본 코드는 [여기](https://github.com/salesforce/LAVIS/tree/5ee63d688ba4cebff63acee04adaef2dee9af207)에서 확인할 수 있습니다.
+
+## 사용 팁[[usage-tips]]
+
+- BLIP-2는 이미지와 조건에 따라 텍스트 프롬프트를 입력받아 조건부 텍스트를 생성합니다. 추론 시 [`generate`] 메소드를 사용하는 것이 권장됩니다.
+- [`Blip2Processor`]를 사용하여 모델에 이미지를 준비하고, 예측된 토큰 ID를 텍스트로 디코딩할 수 있습니다.
+
+## 자료[[resources]]
+
+BLIP-2를 시작하는 데 도움이 되는 공식 Hugging Face 및 커뮤니티(🌎 표시) 자료 목록입니다.
+
+- 이미지 캡셔닝, 시각 질문 응답(VQA), 채팅과 같은 대화형 작업을 위한 BLIP-2 데모 노트북은 [여기](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/BLIP-2)에서 찾을 수 있습니다.
+
+리소스를 제출하여 여기에 포함하고 싶다면 언제든지 풀 리퀘스트를 열어주세요! 리소스는 기존 리소스를 복제하지 않고 새로운 내용이어야 합니다.
+
+## Blip2Config[[transformers.Blip2Config]]
+
+[[autodoc]] Blip2Config
+ - from_vision_qformer_text_configs
+
+## Blip2VisionConfig[[transformers.Blip2VisionConfig]]
+
+[[autodoc]] Blip2VisionConfig
+
+## Blip2QFormerConfig[[transformers.Blip2QFormerConfig]]
+
+[[autodoc]] Blip2QFormerConfig
+
+## Blip2Processor[[transformers.Blip2Processor]]
+
+[[autodoc]] Blip2Processor
+
+## Blip2VisionModel[[transformers.Blip2VisionModel]]
+
+[[autodoc]] Blip2VisionModel
+ - forward
+
+## Blip2QFormerModel[[transformers.Blip2QFormerModel]]
+
+[[autodoc]] Blip2QFormerModel
+ - forward
+
+## Blip2Model[[transformers.Blip2Model]]
+
+[[autodoc]] Blip2Model
+ - forward
+ - get_text_features
+ - get_image_features
+ - get_qformer_features
+
+## Blip2ForConditionalGeneration[[transformers.Blip2ForConditionalGeneration]]
+
+[[autodoc]] Blip2ForConditionalGeneration
+ - forward
+ - generate
+
+## Blip2ForImageTextRetrieval[[transformers.Blip2ForImageTextRetrieval]]
+
+[[autodoc]] Blip2ForImageTextRetrieval
+ - forward
+
+## Blip2TextModelWithProjection[[transformers.Blip2TextModelWithProjection]]
+
+[[autodoc]] Blip2TextModelWithProjection
+
+## Blip2VisionModelWithProjection[[transformers.Blip2VisionModelWithProjection]]
+
+[[autodoc]] Blip2VisionModelWithProjection
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/blip.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/blip.md
new file mode 100644
index 0000000000000000000000000000000000000000..27e085315b891130598a49e4de909ccc28ecc8d5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/blip.md
@@ -0,0 +1,136 @@
+
+
+# BLIP[[blip]]
+
+## 개요[[overview]]
+
+BLIP 모델은 Junnan Li, Dongxu Li, Caiming Xiong, Steven Hoi의 [BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation](https://arxiv.org/abs/2201.12086) 논문에서 제안되었습니다.
+
+BLIP은 여러 멀티모달 작업을 수행할 수 있는 모델입니다:
+
+- 시각 질문 응답 (Visual Question Answering, VQA)
+- 이미지-텍스트 검색 (이미지-텍스트 매칭)
+- 이미지 캡셔닝
+
+논문의 초록은 다음과 같습니다:
+
+*비전-언어 사전 학습(Vision-Language Pre-training, VLP)은 다양한 비전-언어 작업의 성능을 크게 향상시켰습니다. 하지만, 대부분의 기존 사전 학습 모델들은 이해 기반 작업이나 생성 기반 작업 중 하나에서만 뛰어난 성능을 발휘합니다. 또한 성능 향상은 주로 웹에서 수집한 노이즈가 많은 이미지-텍스트 쌍으로 데이터셋의 규모를 키우는 방식으로 이루어졌는데, 이는 최적의 지도 학습 방식이라고 보기 어렵습니다. 본 논문에서는 BLIP이라는 새로운 VLP 프레임워크를 제안합니다. 이 프레임워크는 비전-언어 이해 및 생성 작업 모두에 유연하게 적용될 수 있습니다. BLIP는 캡셔너가 합성 캡션을 생성하고 필터가 노이즈 캡션을 제거하는 부트스트래핑 방법을 통해 웹 데이터의 노이즈를 효과적으로 활용합니다. 우리는 이미지-텍스트 검색(Recall@1에서 +2.7%), 이미지 캡셔닝(CIDEr에서 +2.8%), 그리고 VQA(VQA 점수에서 +1.6%)와 같은 다양한 비전-언어 작업에서 최신 성과를 달성했습니다. 또한 BLIP은 제로샷 방식으로 비디오-언어 작업에 직접 전이될 때도 강력한 일반화 능력을 보여줍니다. 이 논문의 코드, 모델, 데이터셋은 공개되었습니다.*
+
+
+
+이 모델은 [ybelkada](https://huggingface.co/ybelkada)가 기여했습니다.
+원본 코드는 [여기](https://github.com/salesforce/BLIP)에서 찾을 수 있습니다.
+
+## 자료[[resources]]
+
+- [Jupyter notebook](https://github.com/huggingface/notebooks/blob/main/examples/image_captioning_blip.ipynb): 사용자 정의 데이터셋에서 BLIP를 이미지 캡셔닝으로 미세 조정하는 방법
+
+## BlipConfig[[transformers.BlipConfig]]
+
+[[autodoc]] BlipConfig
+ - from_text_vision_configs
+
+## BlipTextConfig[[transformers.BlipTextConfig]]
+
+[[autodoc]] BlipTextConfig
+
+## BlipVisionConfig[[transformers.BlipVisionConfig]]
+
+[[autodoc]] BlipVisionConfig
+
+## BlipProcessor[[transformers.BlipProcessor]]
+
+[[autodoc]] BlipProcessor
+
+## BlipImageProcessor[[transformers.BlipImageProcessor]]
+
+[[autodoc]] BlipImageProcessor
+ - preprocess
+
+
+
+
+## BlipModel[[transformers.BlipModel]]
+
+`BlipModel`은 향후 버전에서 더 이상 지원되지 않을 예정입니다. 목적에 따라 `BlipForConditionalGeneration`, `BlipForImageTextRetrieval` 또는 `BlipForQuestionAnswering`을 사용하십시오.
+
+[[autodoc]] BlipModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## BlipTextModel[[transformers.BlipTextModel]]
+
+[[autodoc]] BlipTextModel
+ - forward
+
+## BlipVisionModel[[transformers.BlipVisionModel]]
+
+[[autodoc]] BlipVisionModel
+ - forward
+
+## BlipForConditionalGeneration[[transformers.BlipForConditionalGeneration]]
+
+[[autodoc]] BlipForConditionalGeneration
+ - forward
+
+## BlipForImageTextRetrieval[[transformers.BlipForImageTextRetrieval]]
+
+[[autodoc]] BlipForImageTextRetrieval
+ - forward
+
+## BlipForQuestionAnswering[[transformers.BlipForQuestionAnswering]]
+
+[[autodoc]] BlipForQuestionAnswering
+ - forward
+
+
+
+
+## TFBlipModel[[transformers.TFBlipModel]]
+
+[[autodoc]] TFBlipModel
+ - call
+ - get_text_features
+ - get_image_features
+
+## TFBlipTextModel[[transformers.TFBlipTextModel]]
+
+[[autodoc]] TFBlipTextModel
+ - call
+
+## TFBlipVisionModel[[transformers.TFBlipVisionModel]]
+
+[[autodoc]] TFBlipVisionModel
+ - call
+
+## TFBlipForConditionalGeneration[[transformers.TFBlipForConditionalGeneration]]
+
+[[autodoc]] TFBlipForConditionalGeneration
+ - call
+
+## TFBlipForImageTextRetrieval[[transformers.TFBlipForImageTextRetrieval]]
+
+[[autodoc]] TFBlipForImageTextRetrieval
+ - call
+
+## TFBlipForQuestionAnswering[[transformers.TFBlipForQuestionAnswering]]
+
+[[autodoc]] TFBlipForQuestionAnswering
+ - call
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/chameleon.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/chameleon.md
new file mode 100644
index 0000000000000000000000000000000000000000..14a18a09765bd4cd737dcf40f0a8ffa82f173e3f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/chameleon.md
@@ -0,0 +1,186 @@
+
+
+# Chameleon [[chameleon]]
+
+## 개요 [[overview]]
+
+Chameleon 모델은 META AI Chameleon 팀의 논문 [Chameleon: Mixed-Modal Early-Fusion Foundation Models](https://arxiv.org/abs/2405.09818v1)에서 제안되었습니다. Chameleon은 벡터 양자화를 사용하여 이미지를 토큰화함으로써 멀티모달 출력을 생성할 수 있는 비전-언어 모델입니다. 이 모델은 교차된 형식을 포함한 이미지와 텍스트를 입력으로 받으며, 텍스트 응답을 생성합니다. 이미지 생성 모듈은 아직 공개되지 않았습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*우리는 이미지와 텍스트를 임의의 순서로 이해하고 생성할 수 있는 early-fusion 토큰 기반의 혼합 모달(mixed-modal) 모델의 일종인 Chameleon을 소개합니다. 우리는 초기부터 안정적인 훈련 접근법, 정렬 방법, 그리고 early-fusion, 토큰 기반, 혼합 모달 설정에 맞춘 아키텍처 매개변수를 제시합니다. 이 모델들은 시각적 질문 응답, 이미지 캡션 생성, 텍스트 생성, 이미지 생성, 장문 혼합 모달 생성 등 포괄적인 작업 범위에서 평가되었습니다. Chameleon은 단일 모델에서 이미지 캡션 생성 작업에서의 최첨단 성능을 포함한 광범위하고 일반적으로 적용 가능한 능력을 보여주며, 텍스트 전용 작업에서 Llama-2를 능가하면서 Mixtral 8x7B와 Gemini-Pro와 같은 모델들 사이에서도 경쟁력을 갖추고 있습니다. 그리고 상당한 성능의 이미지 생성도 수행합니다. 또한 프롬프트나 출력에 이미지와 텍스트의 혼합 시퀀스가 포함된 새로운 장문 혼합 모달 생성 평가에서, 인간의 판단에 따르면 Gemini Pro와 GPT-4V를 포함한 훨씬 더 큰 모델의 성능과 동등하거나 이를 능가합니다. Chameleon은 완전한 멀티모달 문서의 통합 모델링에서 중요한 발전을 보여줍니다.*
+
+Chameleon은 이미지를 이산적인 토큰으로 변환하기 위해 벡터 양자화 모듈을 통합합니다. 이는 자기회귀 transformer를 사용한 이미지 생성을 가능하게 합니다. 원본 논문 에서 가져왔습니다.
+
+이 모델은 [joaogante](https://huggingface.co/joaogante)와 [RaushanTurganbay](https://huggingface.co/RaushanTurganbay)가 기여했습니다. 원본 코드는 [여기](https://github.com/facebookresearch/chameleon)에서 찾을 수 있습니다.
+
+## 사용 팁 [[usage-tips]]
+
+- 더 정확한 결과를 위해, 배치 생성 시 `padding_side="left"`를 사용하는 것을 권장합니다. 생성하기 전에 `processor.tokenizer.padding_side = "left"`로 설정하십시오.
+
+- Chameleon은 안전성 정렬을 위해 튜닝되었음을 유의하십시오. 모델이 응답을 거부하는 경우, 열린 질문보다는 더 구체적으로 질문을 해보세요.
+
+- Chameleon은 채팅 형식으로 생성하므로, 생성된 텍스트는 항상 "assistant's turn"으로 표시됩니다. 프로세서를 호출할 때 `return_for_text_completion=True`를 전달하여 텍스트 완성 생성을 활성화할 수 있습니다.
+
+> [!NOTE]
+> Transformers에서의 Chameleon 구현은 이미지 임베딩을 병합할 위치를 나타내기 위해 특별한 이미지 토큰을 사용합니다. 특별한 이미지 토큰을 위해 새로운 토큰을 추가하지 않고 예약된 토큰 중 하나인 ``를 사용했습니다. 올바른 생성을 위해 프롬프트에서 이미지가 임베딩될 위치에 ``를 추가해야 합니다.
+
+## 사용 예제 [[usage-example]]
+
+### 단일 이미지 추론 [[single-image-inference]]
+
+Chameleon은 게이티드(gated) 모델이므로 Hugging Face Hub에 대한 액세스 권한이 있고 토큰으로 로그인했는지 확인하세요. 다음은 모델을 로드하고 반정밀도(`torch.bfloat16`)로 추론하는 방법입니다:
+
+```python
+from transformers import ChameleonProcessor, ChameleonForConditionalGeneration
+import torch
+from PIL import Image
+import requests
+
+processor = ChameleonProcessor.from_pretrained("facebook/chameleon-7b")
+model = ChameleonForConditionalGeneration.from_pretrained("facebook/chameleon-7b", torch_dtype=torch.bfloat16, device_map="cuda")
+
+# 이미지와 텍스트 프롬프트 준비
+url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+image = Image.open(requests.get(url, stream=True).raw)
+prompt = "이 이미지에서 무엇을 보나요?"
+
+inputs = processor(images=image, text=prompt, return_tensors="pt").to(model.device, dtype=torch.bfloat16)
+
+# 프롬프트를 자기회귀적으로 완성
+output = model.generate(**inputs, max_new_tokens=50)
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+### 다중 이미지 추론 [[multi-image-inference]]
+
+Chameleon은 여러 이미지를 입력으로 받아들이며, 이미지들은 동일한 프롬프트에 속하거나 다른 프롬프트에 속할 수 있습니다(배치 추론에서). 다음은 그 방법입니다:
+
+```python
+from transformers import ChameleonProcessor, ChameleonForConditionalGeneration
+import torch
+from PIL import Image
+import requests
+
+processor = ChameleonProcessor.from_pretrained("facebook/chameleon-7b")
+
+model = ChameleonForConditionalGeneration.from_pretrained("facebook/chameleon-7b", torch_dtype=torch.bfloat16, device_map="cuda")
+
+# 세 가지 다른 이미지 가져오기
+url = "https://www.ilankelman.org/stopsigns/australia.jpg"
+image_stop = Image.open(requests.get(url, stream=True).raw)
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image_cats = Image.open(requests.get(url, stream=True).raw)
+
+url = "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg"
+image_snowman = Image.open(requests.get(url, stream=True).raw)
+
+# 배치된 프롬프트 준비: 첫 번째는 다중 이미지 프롬프트이고 두 번째는 단일 이미지 프롬프트입니다
+prompts = [
+ "이 이미지들은 무엇이 공통점인가요?",
+ "이 이미지에 무엇이 나타나 있나요?"
+]
+
+# 이미지들을 텍스트 프롬프트에서 사용되어야 하는 순서대로 입력할 수 있습니다
+# 각 "" 토큰은 하나의 이미지를 사용하며, 다음 "" 토큰은 다음 이미지를 사용합니다
+inputs = processor(images=[image_stop, image_cats, image_snowman], text=prompts, padding=True, return_tensors="pt").to(device="cuda", dtype=torch.bfloat16)
+
+# 생성
+generate_ids = model.generate(**inputs, max_new_tokens=50)
+processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)
+```
+
+## 모델 최적화 [[model-optimization]]
+
+### Bitsandbytes를 사용한 양자화 [[quantization-using-bitsandbytes]]
+
+모델은 8비트 또는 4비트로 로드할 수 있으며, 이는 원본 모델의 성능을 유지하면서 메모리 요구 사항을 크게 줄여줍니다. 먼저 bitsandbytes를 설치하고(`pip install bitsandbytes`), 라이브러리가 지원하는 GPU/가속기를 사용 중인지 확인하십시오.
+
+
+
+bitsandbytes는 CUDA 이외의 여러 백엔드를 지원하도록 리팩터링되고 있습니다. 현재 ROCm(AMD GPU) 및 Intel CPU 구현이 성숙 단계이며, Intel XPU는 진행 중이고 Apple Silicon 지원은 Q4/Q1에 예상됩니다. 설치 지침 및 최신 백엔드 업데이트는 [이 링크](https://huggingface.co/docs/bitsandbytes/main/en/installation#multi-backend)를 방문하세요.
+
+전체 공개 전에 버그를 식별하는 데 도움이 되는 피드백을 환영합니다! 자세한 내용과 피드백은 [이 문서](https://huggingface.co/docs/bitsandbytes/main/en/non_cuda_backends)를 확인하세요.
+
+
+
+위의 코드 스니펫을 다음과 같이 변경하면 됩니다:
+
+```python
+from transformers import ChameleonForConditionalGeneration, BitsAndBytesConfig
+
+# 모델 양자화 방식 지정
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype=torch.bfloat16,
+)
+
+model = ChameleonForConditionalGeneration.from_pretrained("facebook/chameleon-7b", quantization_config=quantization_config, device_map="cuda")
+```
+
+### Flash-Attention 2와 SDPA를 사용하여 생성 속도 향상 [[use-flash-attention-2-and-sdpa-to-further-speed-up-generation]]
+
+이 모델은 최적화를 위해 Flash-Attention 2와 PyTorch의 [`torch.nn.functional.scaled_dot_product_attention`](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention.html)를 모두 지원합니다. SDPA는 모델을 로드할 때 기본 옵션입니다. Flash Attention 2로 전환하려면 먼저 flash-attn을 설치해야 합니다. 해당 패키지 설치에 대해서는 [원본 리포지토리](https://github.com/Dao-AILab/flash-attention)를 참고하십시오. 위의 코드 스니펫을 다음과 같이 변경하면 됩니다:
+
+```python
+from transformers import ChameleonForConditionalGeneration
+
+model_id = "facebook/chameleon-7b"
+model = ChameleonForConditionalGeneration.from_pretrained(
+ model_id,
+ torch_dtype=torch.bfloat16,
+ low_cpu_mem_usage=True,
+ attn_implementation="flash_attention_2"
+).to(0)
+```
+
+## ChameleonConfig [[transformers.ChameleonConfig]]
+
+[[autodoc]] ChameleonConfig
+
+## ChameleonVQVAEConfig [[transformers.ChameleonVQVAEConfig]]
+
+[[autodoc]] ChameleonVQVAEConfig
+
+## ChameleonProcessor [[transformers.ChameleonProcessor]]
+
+[[autodoc]] ChameleonProcessor
+
+## ChameleonImageProcessor [[transformers.ChameleonImageProcessor]]
+
+[[autodoc]] ChameleonImageProcessor
+ - preprocess
+
+## ChameleonVQVAE [[transformers.ChameleonVQVAE]]
+
+[[autodoc]] ChameleonVQVAE
+ - forward
+
+## ChameleonModel [[transformers.ChameleonModel]]
+
+[[autodoc]] ChameleonModel
+ - forward
+
+## ChameleonForConditionalGeneration [[transformers.ChameleonForConditionalGeneration]]
+
+[[autodoc]] ChameleonForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/clip.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/clip.md
new file mode 100644
index 0000000000000000000000000000000000000000..5c19a31e10e658a694464cb079b513f5fccf62f6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/clip.md
@@ -0,0 +1,318 @@
+
+
+# CLIP[[clip]]
+
+## 개요[[overview]]
+
+CLIP 모델은 Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh,
+Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever가 제안한 [자연어 지도(supervision)를 통한 전이 가능한 시각 모델 학습](https://arxiv.org/abs/2103.00020)라는 논문에서 소개되었습니다. CLIP(Contrastive Language-Image Pre-Training)은 다양한 이미지와 텍스트 쌍으로 훈련된 신경망 입니다. GPT-2와 3의 제로샷 능력과 유사하게, 해당 작업에 직접적으로 최적화하지 않고도 주어진 이미지에 대해 가장 관련성 있는 텍스트 스니펫을 예측하도록 자연어로 지시할 수 있습니다.
+
+해당 논문의 초록입니다.
+
+*최신 컴퓨터 비전 시스템은 미리 정해진 고정된 객체 카테고리 집합을 예측하도록 훈련됩니다. 이러한 제한된 형태의 지도는 다른 시각적 개념을 지정하기 위해 추가적인 라벨링된 데이터가 필요하므로 그 일반성과 사용성을 제한합니다. 이미지 원시 텍스트에서 직접 학습하는 것은 훨씬 더 광범위한 지도 소스를 활용하는 아주 좋은 대안입니다. 이미지와 캡션을 맞추는 간단한 사전 학습 작업이, 인터넷에서 수집한 4억 쌍의 이미지-텍스트 데이터셋에서 SOTA 수준의 이미지 표현을 처음부터 효율적이고 확장 가능하게 학습하는 방법임을 확인할 수 있습니다. 사전 훈련 후, 자연어는 학습된 시각적 개념을 참조하거나 새로운 개념을 설명하는 데 사용되어 모델의 하위 작업으로의 제로샷 전이를 가능하게 합니다. 해당 논문에서는 OCR, 비디오 내 행동 인식, 지리적 위치 파악, 그리고 많은 종류의 세밀한 객체 분류 등 30개 이상의 다양한 기존 컴퓨터 비전 데이터셋에 대한 벤치마킹을 통해 이 접근 방식의 성능을 연구합니다. 이 모델은 대부분의 작업에 대해 의미 있게 전이되며, 종종 데이터셋별 훈련 없이도 완전 지도 학습 기준선과 경쟁력 있는 성능을 보입니다. 예를 들어, ImageNet에서 원래 ResNet-50의 정확도를 제로샷으로 일치시키는데, 이는 ResNet-50이 훈련된 128만 개의 훈련 예제를 전혀 사용할 필요가 없었습니다. 코드 및 사전 훈련된 모델 가중치는 이 https URL에서 공개합니다.*
+
+이 모델은 [valhalla](https://huggingface.co/valhalla)에 의해 기여되었습니다.
+원본 코드는 [이곳](https://github.com/openai/CLIP)에서 확인할 수 있습니다.
+
+## 사용 팁과 예시[[usage-tips-and-example]]
+
+CLIP은 멀티모달 비전 밒 언어 모델입니다. 이미지-텍스트 유사도 계산과 제로샷 이미지 분류에 사용될 수 있습니다. CLIP은 ViT와 유사한 트랜스포머를 사용하여 시각적 특징을 추출하고, 인과적 언어 모델을 사용하여 텍스트 특징을 추출합니다. 그 후 텍스트와 시각적 특징 모두 동일한 차원의 잠재(latent) 공간으로 투영됩니다. 투영된 이미지와 텍스트 특징 사이의 내적이 유사도 점수로 사용됩니다.
+
+트랜스포머 인코더에 이미지를 입력하기 위해, 각 이미지는 고정 크기의 겹치지 않는 패치들의 시퀀스로 분할되고, 이후 선형 임베딩됩니다. [CLS]토큰이 전체 이미지의 표현으로 추가됩니다. 저자들은 또한 절대 위치 임베딩을 추가하고, 결과로 나온 벡터 시퀀스를 표준 트랜스포머 인토더에 입력합니다. [`CLIPImageProcessor`]는 모델을 위해 이미지를 리사이즈(또는 재스캐일링)하고 정규화하는데 사용될 수 있습니다.
+
+[`CLIPTokenizer`]는 텍스트를 인코딩하는데 사용됩니다. [`CLIPProcessor`]는 [`CLIPImageProcessor`]와 [`CLIPTokenizer`]를 하나의 인스턴스로 감싸서 텍스트를 인코딩하고 이미지를 준비하는데 모두 사용됩니다.
+
+다음 예시는 [`CLIPProcessor`]와 [`CLIPModel`]을 사용하여 이미지-텍스트 유사도 점수를 얻는 방법을 보여줍니다.
+
+
+```python
+>>> from PIL import Image
+>>> import requests
+
+>>> from transformers import CLIPProcessor, CLIPModel
+
+>>> model = CLIPModel.from_pretrained("openai/clip-vit-base-patch32")
+>>> processor = CLIPProcessor.from_pretrained("openai/clip-vit-base-patch32")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> inputs = processor(text=["a photo of a cat", "a photo of a dog"], images=image, return_tensors="pt", padding=True)
+
+>>> outputs = model(**inputs)
+>>> logits_per_image = outputs.logits_per_image # 이미지-텍스트 유사성 점수
+>>> probs = logits_per_image.softmax(dim=1) # 확률을 레이블링 하기위해서 소프트맥스를 취합니다.
+```
+
+
+### CLIP과 플래시 어텐션2 결합[[combining-clip-and-flash-attention-2]]
+
+먼저 최신버전의 플래시 어텐션2를 설치합니다.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+플래시 어텐션2와 호환되는 하드웨어를 가지고 있는지 확인하세요. 이에 대한 자세한 내용은 flash-attn 리포지토리의 공식문서에서 확인할 수 있습니다. 또한 모델을 반정밀도(`torch.float16`)로 로드하는 것을 잊지 마세요.
+
+
+
+작은 배치 크기를 사용할 때, 플래시 어텐션을 사용하면 모델이 느려지는 것을 느낄 수 있습니다.아래의 [플래시 어텐션과 SDPA를 사용한 예상 속도 향상](#Expected-speedups-with-Flash-Attention-and-SDPA) 섹션을 참조하여 적절한 어텐션 구현을 선택하세요.
+
+
+
+플래시 어텐션2를 사용해서 모델을 로드하고 구동하기 위해서 다음 스니펫을 참고하세요:
+
+```python
+>>> import torch
+>>> import requests
+>>> from PIL import Image
+
+>>> from transformers import CLIPProcessor, CLIPModel
+
+>>> device = "cuda"
+>>> torch_dtype = torch.float16
+
+>>> model = CLIPModel.from_pretrained(
+... "openai/clip-vit-base-patch32",
+... attn_implementation="flash_attention_2",
+... device_map=device,
+... torch_dtype=torch_dtype,
+... )
+>>> processor = CLIPProcessor.from_pretrained("openai/clip-vit-base-patch32")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> inputs = processor(text=["a photo of a cat", "a photo of a dog"], images=image, return_tensors="pt", padding=True)
+>>> inputs.to(device)
+
+>>> with torch.no_grad():
+... with torch.autocast(device):
+... outputs = model(**inputs)
+
+>>> logits_per_image = outputs.logits_per_image # 이미지-텍스트 유사성 점수
+>>> probs = logits_per_image.softmax(dim=1) # 확률을 레이블링 하기위해서 소프트맥스를 취합니다.
+>>> print(probs)
+tensor([[0.9946, 0.0052]], device='cuda:0', dtype=torch.float16)
+```
+
+
+### 스케일된 내적 어텐션 (Scaled dot-product Attention(SDPA)) 사용하기[[using-scaled-dot-product-attention-sdpa]]
+
+파이토치는 `torch.nn.functional`의 일부로 네이티브 스케일된 내적 어텐션(SPDA) 연산자를 포함하고 있습니다. 이 함수는 입력과 사용 중인 하드웨어에 따라 적용될 수 있는 여러 구현을 포함합니다. 자세한 정보는 [공식문서](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)나 [GPU 추론](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention) 페이지를 참조하세요.
+
+`torch>=2.1.1`에서는 구현이 가능할 때 SDPA가 기본적으로 사용되지만, `from_pretrained()` 함수에서 `attn_implementation="sdpa"`를 설정하여 SDPA를 명시적으로 사용하도록 요청할 수도 있습니다.
+
+```python
+from transformers import CLIPModel
+
+model = CLIPModel.from_pretrained("openai/clip-vit-base-patch32", torch_dtype=torch.float16, attn_implementation="sdpa")
+```
+
+최고의 속도향상을 위해서, 반정밀도로 모델을 로드하는 것을 추천합니다. (예를들면 `torch.float16` 또는 `torch.bfloat16`).
+
+### 플래시 어텐션과 스케일된 내적 어텐션(SDPA)으로 인해 예상되는 속도향상[[expected-speedups-with-flash-attention-and-sdpa]]
+
+로컬 벤치마크(NVIDIA A10G, PyTorch 2.3.1+cu121)에서 `float16`을 사용하여 `"openai/clip-vit-large-patch14"` 체크포인트로 추론을 수행했을 때, 다음과 같은 속도 향상을 확인 했습니다.
+[코드](https://gist.github.com/qubvel/ac691a54e54f9fae8144275f866a7ff8):
+
+#### CLIPTextModel[[cliptextmodel]]
+
+| Num text labels | Eager (s/iter) | FA2 (s/iter) | FA2 speedup | SDPA (s/iter) | SDPA speedup |
+|------------------:|-----------------:|---------------:|--------------:|----------------:|---------------:|
+| 4 | 0.009 | 0.012 | 0.737 | 0.007 | 1.269 |
+| 16 | 0.009 | 0.014 | 0.659 | 0.008 | 1.187 |
+| 32 | 0.018 | 0.021 | 0.862 | 0.016 | 1.142 |
+| 64 | 0.034 | 0.034 | 1.001 | 0.03 | 1.163 |
+| 128 | 0.063 | 0.058 | 1.09 | 0.054 | 1.174 |
+
+
+
+#### CLIPVisionModel[[clipvisionmodel]]
+
+| Image batch size | Eager (s/iter) | FA2 (s/iter) | FA2 speedup | SDPA (s/iter) | SDPA speedup |
+|-------------------:|-----------------:|---------------:|--------------:|----------------:|---------------:|
+| 1 | 0.016 | 0.013 | 1.247 | 0.012 | 1.318 |
+| 4 | 0.025 | 0.021 | 1.198 | 0.021 | 1.202 |
+| 16 | 0.093 | 0.075 | 1.234 | 0.075 | 1.24 |
+| 32 | 0.181 | 0.147 | 1.237 | 0.146 | 1.241 |
+
+
+
+#### CLIPModel[[clipmodel]]
+
+| Image batch size | Num text labels | Eager (s/iter) | FA2 (s/iter) | FA2 speedup | SDPA (s/iter) | SDPA speedup |
+|-------------------:|------------------:|-----------------:|---------------:|--------------:|----------------:|---------------:|
+| 1 | 4 | 0.025 | 0.026 | 0.954 | 0.02 | 1.217 |
+| 1 | 16 | 0.026 | 0.028 | 0.918 | 0.02 | 1.287 |
+| 1 | 64 | 0.042 | 0.046 | 0.906 | 0.036 | 1.167 |
+| 4 | 4 | 0.028 | 0.033 | 0.849 | 0.024 | 1.189 |
+| 4 | 16 | 0.034 | 0.035 | 0.955 | 0.029 | 1.169 |
+| 4 | 64 | 0.059 | 0.055 | 1.072 | 0.05 | 1.179 |
+| 16 | 4 | 0.096 | 0.088 | 1.091 | 0.078 | 1.234 |
+| 16 | 16 | 0.102 | 0.09 | 1.129 | 0.083 | 1.224 |
+| 16 | 64 | 0.127 | 0.11 | 1.157 | 0.105 | 1.218 |
+| 32 | 4 | 0.185 | 0.159 | 1.157 | 0.149 | 1.238 |
+| 32 | 16 | 0.19 | 0.162 | 1.177 | 0.154 | 1.233 |
+| 32 | 64 | 0.216 | 0.181 | 1.19 | 0.176 | 1.228 |
+
+## 자료[[resources]]
+
+CLIP을 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다.
+
+- [원격 센싱 (인공위성) 이미지와 캡션을 가지고 CLIP 미세조정하기](https://huggingface.co/blog/fine-tune-clip-rsicd):
+[RSICD dataset](https://github.com/201528014227051/RSICD_optimal)을 가지고 CLIP을 미세조정 하는 방법과 데이터 증강에 대한 성능 비교에 대한 블로그 포스트
+- 이 [예시 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/contrastive-image-text)는 [COCO dataset](https://cocodataset.org/#home)를 이용한 사전학습된 비전과 텍스트와 인코더를 사용해서 CLIP같은 비전-텍스트 듀얼 모델을 어떻게 학습시키는지 보여줍니다.
+
+
+
+
+## CLIPModel[[transformers.CLIPModel]]
+
+[[autodoc]] CLIPModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## CLIPTextModel[[transformers.CLIPTextModel]]
+
+[[autodoc]] CLIPTextModel
+ - forward
+
+## CLIPTextModelWithProjection[[transformers.CLIPTextModelWithProjection]]
+
+[[autodoc]] CLIPTextModelWithProjection
+ - forward
+
+## CLIPVisionModelWithProjection[[transformers.CLIPVisionModelWithProjection]]
+
+[[autodoc]] CLIPVisionModelWithProjection
+ - forward
+
+## CLIPVisionModel[[transformers.CLIPVisionModel]]
+
+[[autodoc]] CLIPVisionModel
+ - forward
+
+## CLIPForImageClassification[[transformers.CLIPForImageClassification]]
+
+[[autodoc]] CLIPForImageClassification
+ - forward
+
+
+
+
+## TFCLIPModel[[transformers.TFCLIPModel]]
+
+[[autodoc]] TFCLIPModel
+ - call
+ - get_text_features
+ - get_image_features
+
+## TFCLIPTextModel[[transformers.TFCLIPTextModel]]
+
+[[autodoc]] TFCLIPTextModel
+ - call
+
+## TFCLIPVisionModel[[transformers.TFCLIPVisionModel]]
+
+[[autodoc]] TFCLIPVisionModel
+ - call
+
+
+
+
+## FlaxCLIPModel[[transformers.FlaxCLIPModel]]
+
+[[autodoc]] FlaxCLIPModel
+ - __call__
+ - get_text_features
+ - get_image_features
+
+## FlaxCLIPTextModel[[transformers.FlaxCLIPTextModel]]
+
+[[autodoc]] FlaxCLIPTextModel
+ - __call__
+
+## FlaxCLIPTextModelWithProjection[[transformers.FlaxCLIPTextModelWithProjection]]
+
+[[autodoc]] FlaxCLIPTextModelWithProjection
+ - __call__
+
+## FlaxCLIPVisionModel[[transformers.FlaxCLIPVisionModel]]
+
+[[autodoc]] FlaxCLIPVisionModel
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/cohere.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/cohere.md
new file mode 100644
index 0000000000000000000000000000000000000000..c577764623f49672a27b78f850828cc21fa7a37b
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/cohere.md
@@ -0,0 +1,139 @@
+# Cohere[[cohere]]
+
+## 개요[[overview]]
+
+The Cohere Command-R 모델은 Cohere팀이 [Command-R: 프로덕션 규모의 검색 증강 생성](https://txt.cohere.com/command-r/)라는 블로그 포스트에서 소개 되었습니다.
+
+논문 초록:
+
+*Command-R은 기업의 프로덕션 규모 AI를 가능하게 하기 위해 RAG(검색 증강 생성)와 도구 사용을 목표로 하는 확장 가능한 생성 모델입니다. 오늘 우리는 대규모 프로덕션 워크로드를 목표로 하는 새로운 LLM인 Command-R을 소개합니다. Command-R은 높은 효율성과 강력한 정확성의 균형을 맞추는 '확장 가능한' 모델 카테고리를 대상으로 하여, 기업들이 개념 증명을 넘어 프로덕션 단계로 나아갈 수 있게 합니다.*
+
+*Command-R은 검색 증강 생성(RAG)이나 외부 API 및 도구 사용과 같은 긴 문맥 작업에 최적화된 생성 모델입니다. 이 모델은 RAG 애플리케이션을 위한 최고 수준의 통합을 제공하고 기업 사용 사례에서 뛰어난 성능을 발휘하기 위해 우리의 업계 선도적인 Embed 및 Rerank 모델과 조화롭게 작동하도록 설계되었습니다. 기업이 대규모로 구현할 수 있도록 만들어진 모델로서, Command-R은 다음과 같은 특징을 자랑합니다:
+- RAG 및 도구 사용에 대한 강력한 정확성
+- 낮은 지연 시간과 높은 처리량
+- 더 긴 128k 컨텍스트와 낮은 가격
+- 10개의 주요 언어에 걸친 강력한 기능
+- 연구 및 평가를 위해 HuggingFace에서 사용 가능한 모델 가중치
+
+모델 체크포인트는 [이곳](https://huggingface.co/CohereForAI/c4ai-command-r-v01)에서 확인하세요.
+이 모델은 [Saurabh Dash](https://huggingface.co/saurabhdash)과 [Ahmet Üstün](https://huggingface.co/ahmetustun)에 의해 기여 되었습니다. Hugging Face에서 이 코드의 구현은 [GPT-NeoX](https://github.com/EleutherAI/gpt-neox)에 기반하였습니다.
+
+## 사용 팁[[usage-tips]]
+
+
+
+Hub에 업로드된 체크포인트들은 `torch_dtype = 'float16'`을 사용합니다.
+이는 `AutoModel` API가 체크포인트를 `torch.float32`에서 `torch.float16`으로 변환하는 데 사용됩니다.
+
+온라인 가중치의 `dtype`은 `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`를 사용하여 모델을 초기화할 때 `torch_dtype="auto"`를 사용하지 않는 한 대부분 무관합니다. 그 이유는 모델이 먼저 다운로드되고(온라인 체크포인트의 `dtype` 사용), 그 다음 `torch`의 기본 `dtype`으로 변환되며(이때 `torch.float32`가 됨), 마지막으로 config에 `torch_dtype`이 제공된 경우 이를 사용하기 때문입니다.
+
+모델을 `float16`으로 훈련하는 것은 권장되지 않으며 `nan`을 생성하는 것으로 알려져 있습니다. 따라서 모델은 `bfloat16`으로 훈련해야 합니다.
+
+모델과 토크나이저는 다음과 같이 로드할 수 있습니다:
+
+```python
+# pip install transformers
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+model_id = "CohereForAI/c4ai-command-r-v01"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id)
+
+# Format message with the command-r chat template
+messages = [{"role": "user", "content": "Hello, how are you?"}]
+input_ids = tokenizer.apply_chat_template(messages, tokenize=True, add_generation_prompt=True, return_tensors="pt")
+## <|START_OF_TURN_TOKEN|><|USER_TOKEN|>Hello, how are you?<|END_OF_TURN_TOKEN|><|START_OF_TURN_TOKEN|><|CHATBOT_TOKEN|>
+
+gen_tokens = model.generate(
+ input_ids,
+ max_new_tokens=100,
+ do_sample=True,
+ temperature=0.3,
+ )
+
+gen_text = tokenizer.decode(gen_tokens[0])
+print(gen_text)
+```
+
+- Flash Attention 2를 `attn_implementation="flash_attention_2"`를 통해 사용할 때는, `from_pretrained` 클래스 메서드에 `torch_dtype`을 전달하지 말고 자동 혼합 정밀도 훈련(Automatic Mixed-Precision training)을 사용하세요. `Trainer`를 사용할 때는 단순히 `fp16` 또는 `bf16`을 `True`로 지정하면 됩니다. 그렇지 않은 경우에는 `torch.autocast`를 사용하고 있는지 확인하세요. 이는 Flash Attention이 `fp16`와 `bf16` 데이터 타입만 지원하기 때문에 필요합니다.
+
+## 리소스[[resources]]
+
+Command-R을 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+
+<|START_OF_TURN_TOKEN|><|USER_TOKEN|>Hello, how are you?<|END_OF_TURN_TOKEN|><|START_OF_TURN_TOKEN|><|CHATBOT_TOKEN|>
+
+gen_tokens = model.generate(
+ input_ids,
+ max_new_tokens=100,
+ do_sample=True,
+ temperature=0.3,
+ )
+
+gen_text = tokenizer.decode(gen_tokens[0])
+print(gen_text)
+```
+
+bitsandbytes 라이브러리를 이용해서 4bit 양자화된 모델 로딩
+```python
+# pip install transformers bitsandbytes accelerate
+from transformers import AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig
+
+bnb_config = BitsAndBytesConfig(load_in_4bit=True)
+
+model_id = "CohereForAI/c4ai-command-r-v01"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=bnb_config)
+
+gen_tokens = model.generate(
+ input_ids,
+ max_new_tokens=100,
+ do_sample=True,
+ temperature=0.3,
+ )
+
+gen_text = tokenizer.decode(gen_tokens[0])
+print(gen_text)
+```
+
+
+## CohereConfig[[transformers.CohereConfig]]
+
+[[autodoc]] CohereConfig
+
+## CohereTokenizerFast[[transformers.CohereTokenizerFast]]
+
+[[autodoc]] CohereTokenizerFast
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - update_post_processor
+ - save_vocabulary
+
+## CohereModel[[transformers.CohereModel]]
+
+[[autodoc]] CohereModel
+ - forward
+
+
+## CohereForCausalLM[[transformers.CohereForCausalLM]]
+
+[[autodoc]] CohereForCausalLM
+ - forward
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/convbert.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/convbert.md
new file mode 100644
index 0000000000000000000000000000000000000000..ec64a369b56a3f0e33f9e41c44f6b95555dc36dd
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/convbert.md
@@ -0,0 +1,135 @@
+
+
+# ConvBERT [[convbert]]
+
+
+
+## 개요 [[overview]]
+
+ConvBERT 모델은 Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan에 의해 제안되었으며, 제안 논문 제목은 [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496)입니다.
+
+논문의 초록은 다음과 같습니다:
+
+*BERT와 그 변형 모델과 같은 사전 학습된 언어 모델들은 최근 다양한 자연어 이해 과제에서 놀라운 성과를 이루었습니다. 그러나 BERT는 글로벌 셀프 어텐션 블록에 크게 의존하기 때문에 메모리 사용량이 많고 계산 비용이 큽니다. 모든 어텐션 헤드가 글로벌 관점에서 어텐션 맵을 생성하기 위해 입력 시퀀스 전체를 탐색하지만, 일부 헤드는 로컬 종속성만 학습할 필요가 있다는 것을 발견했습니다. 이는 불필요한 계산이 포함되어 있음을 의미합니다. 따라서 우리는 이러한 self-attention 헤드들을 대체하여 로컬 종속성을 직접 모델링하기 위해 새로운 span 기반 동적 컨볼루션을 제안합니다. 새로운 컨볼루션 헤드와 나머지 self-attention 헤드들이 결합하여 글로벌 및 로컬 문맥 학습에 더 효율적인 혼합 어텐션 블록을 구성합니다. 우리는 BERT에 이 혼합 어텐션 설계를 적용하여 ConvBERT 모델을 구축했습니다. 실험 결과, ConvBERT는 다양한 다운스트림 과제에서 BERT 및 그 변형 모델보다 더 우수한 성능을 보였으며, 훈련 비용과 모델 파라미터 수가 더 적었습니다. 특히 ConvBERTbase 모델은 GLUE 스코어 86.4를 달성하여 ELECTRAbase보다 0.7 높은 성과를 보이며, 훈련 비용은 1/4 이하로 줄었습니다. 코드와 사전 학습된 모델은 공개될 예정입니다.*
+
+이 모델은 [abhishek](https://huggingface.co/abhishek)에 의해 기여되었으며, 원본 구현은 여기에서 찾을 수 있습니다 : https://github.com/yitu-opensource/ConvBert
+
+
+
+## 사용 팁 [[usage-tips]]
+ConvBERT 훈련 팁은 BERT와 유사합니다. 사용 팁은 [BERT 문서](bert).를 참고하십시오.
+
+
+## 리소스 [[resources]]
+
+- [텍스트 분류 작업 가이드 (Text classification task guide)](../tasks/sequence_classification)
+- [토큰 분류 작업 가이드 (Token classification task guide)](../tasks/token_classification)
+- [질의응답 작업 가이드 (Question answering task guide)](../tasks/question_answering)
+- [마스킹된 언어 모델링 작업 가이드 (Masked language modeling task guide)](../tasks/masked_language_modeling)
+- [다중 선택 작업 가이드 (Multiple choice task guide)](../tasks/multiple_choice)
+
+## ConvBertConfig [[transformers.ConvBertConfig]]
+
+[[autodoc]] ConvBertConfig
+
+## ConvBertTokenizer [[transformers.ConvBertTokenizer]]
+
+[[autodoc]] ConvBertTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## ConvBertTokenizerFast [[transformers.ConvBertTokenizerFast]]
+
+[[autodoc]] ConvBertTokenizerFast
+
+
+
+
+## ConvBertModel [[transformers.ConvBertModel]]
+
+[[autodoc]] ConvBertModel
+ - forward
+
+## ConvBertForMaskedLM [[transformers.ConvBertForMaskedLM]]
+
+[[autodoc]] ConvBertForMaskedLM
+ - forward
+
+## ConvBertForSequenceClassification [[transformers.ConvBertForSequenceClassification]]
+
+[[autodoc]] ConvBertForSequenceClassification
+ - forward
+
+## ConvBertForMultipleChoice [[transformers.ConvBertForMultipleChoice]]
+
+[[autodoc]] ConvBertForMultipleChoice
+ - forward
+
+## ConvBertForTokenClassification [[transformers.ConvBertForTokenClassification]]
+
+[[autodoc]] ConvBertForTokenClassification
+ - forward
+
+## ConvBertForQuestionAnswering [[transformers.ConvBertForQuestionAnswering]]
+
+[[autodoc]] ConvBertForQuestionAnswering
+ - forward
+
+
+
+
+## TFConvBertModel [[transformers.TFConvBertModel]]
+
+[[autodoc]] TFConvBertModel
+ - call
+
+## TFConvBertForMaskedLM [[transformers.TFConvBertForMaskedLM]]
+
+[[autodoc]] TFConvBertForMaskedLM
+ - call
+
+## TFConvBertForSequenceClassification [[transformers.TFConvBertForSequenceClassification]]
+
+[[autodoc]] TFConvBertForSequenceClassification
+ - call
+
+## TFConvBertForMultipleChoice [[transformers.TFConvBertForMultipleChoice]]
+
+[[autodoc]] TFConvBertForMultipleChoice
+ - call
+
+## TFConvBertForTokenClassification [[transformers.TFConvBertForTokenClassification]]
+
+[[autodoc]] TFConvBertForTokenClassification
+ - call
+
+## TFConvBertForQuestionAnswering [[transformers.TFConvBertForQuestionAnswering]]
+
+[[autodoc]] TFConvBertForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/dbrx.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/dbrx.md
new file mode 100644
index 0000000000000000000000000000000000000000..4b33e95700691edd07f82c989c9c07e36aa0b419
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/dbrx.md
@@ -0,0 +1,125 @@
+
+
+# DBRX[[dbrx]]
+
+## 개요[[overview]]
+
+DBRX는 [트랜스포머 기반의](https://www.isattentionallyouneed.com/) 다음 토큰을 예측하는 디코더 전용 LLM 모델입니다.
+총 132B 매개변수를 가진 *세밀한* 전문가 혼합(MoE) 아키텍처를 사용하며, 이 중 36B 매개변수가 입력마다 활성화됩니다.
+12T 토큰의 텍스트와 코드 데이터로 사전 학습되었습니다.
+
+Mixtral-8x7B와 Grok-1과 같은 다른 공개 MoE 모델들과 비교했을 때, DBRX는 더 많은 수의 작은 전문가들을 사용하는 세밀한 구조를 가지고 있습니다. DBRX는 16개의 전문가 중 4개를 선택하는 반면, Mixtral-8x7B와 Grok-1은 8개의 전문가 중 2개를 선택합니다.
+
+이는 65배 더 많은 전문가 조합을 가능하게 하며, 이를 통해 모델의 품질이 향상되는 것을 발견했습니다.
+DBRX는 회전 위치 인코딩(RoPE), 게이트 선형 유닛(GLU), 그룹 쿼리 어텐션(GQA)을 사용합니다.
+BPE 기반 모델이며 [tiktoken](https://github.com/openai/tiktoken) 저장소에 설명된 GPT-4 토크나이저를 사용합니다.
+이러한 선택들은 철저한 평가와 스케일링 실험을 기반으로 이루어졌습니다.
+
+DBRX는 신중하게 선별된 12T 토큰의 데이터로 사전 학습되었으며, 최대 문맥 길이는 32K 토큰입니다.
+이 데이터는 토큰 대비 MPT 계열 모델 학습에 사용된 데이터보다 최소 2배 이상 더 좋은 것으로 추정됩니다.
+이 새로운 데이터셋은 데이터 처리를 위한 Apache Spark™와 Databricks 노트북, 그리고 데이터 관리와 거버넌스를 위한 Unity Catalog를 포함한 Databricks 도구 전체를 활용하여 개발되었습니다.
+우리는 사전 학습을 위해 커리큘럼 학습을 사용했으며, 학습 중 데이터 믹스를 변경하는 방식이 모델 품질을 상당히 개선한다는 것을 발견했습니다.
+
+
+DBRX Instruct와 DBRX Base에 대한 더 자세한 정보는 이 [기술 블로그 포스트](https://www.databricks.com/blog/introducing-dbrx-new-state-art-open-llm)에서 확인할 수 있습니다.
+
+이 모델은 [eitan-turok](https://huggingface.co/eitanturok)와 [abhi-db](https://huggingface.co/abhi-db)가 기여했습니다. 원본 코드는 [이곳](https://github.com/databricks/dbrx-instruct)에서 찾을 수 있지만, 최신 버전이 아닐 수 있습니다.
+
+## 사용 예[[usage-examples]]
+
+`generate()` 메소드는 DBRX를 사용하여 텍스트를 생성하는 데 사용될 수 있습니다. 표준 어텐션 구현, 플래시 어텐션, PyTorch의 스케일된 내적 어텐션(Scaled Dot-Product Attention)을 사용하여 생성할 수 있습니다. 후자의 두 어텐션 구현 방식은 처리 속도를 크게 높여줍니다.
+
+```python
+from transformers import DbrxForCausalLM, AutoTokenizer
+import torch
+
+tokenizer = AutoTokenizer.from_pretrained("databricks/dbrx-instruct", token="YOUR_HF_TOKEN")
+model = DbrxForCausalLM.from_pretrained(
+ "databricks/dbrx-instruct",
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+ token="YOUR_HF_TOKEN",
+ )
+
+input_text = "What does it take to build a great LLM?"
+messages = [{"role": "user", "content": input_text}]
+input_ids = tokenizer.apply_chat_template(messages, return_dict=True, tokenize=True, add_generation_prompt=True, return_tensors="pt").to("cuda")
+
+outputs = model.generate(**input_ids, max_new_tokens=200)
+print(tokenizer.decode(outputs[0]))
+```
+
+`pip install flash-attn`를 통해 플래시 어텐션을 설치하면, 더 빠른 생성이 가능합니다. (플래시 어텐션에 대한 HuggingFace 문서는 [이곳](https://huggingface.co/docs/transformers/perf_infer_gpu_one#flashattention-2)에서 확인할 수 있습니다.)
+
+
+```python
+from transformers import DbrxForCausalLM, AutoTokenizer
+import torch
+
+tokenizer = AutoTokenizer.from_pretrained("databricks/dbrx-instruct", token="YOUR_HF_TOKEN")
+model = DbrxForCausalLM.from_pretrained(
+ "databricks/dbrx-instruct",
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+ token="YOUR_HF_TOKEN",
+ attn_implementation="flash_attention_2",
+ )
+
+input_text = "What does it take to build a great LLM?"
+messages = [{"role": "user", "content": input_text}]
+input_ids = tokenizer.apply_chat_template(messages, return_dict=True, tokenize=True, add_generation_prompt=True, return_tensors="pt").to("cuda")
+
+outputs = model.generate(**input_ids, max_new_tokens=200)
+print(tokenizer.decode(outputs[0]))
+```
+
+PyTorch의 스케일된 내적 어텐션을 사용하여도 더 빠른 생성이 가능합니다. (스케일된 내적 어텐션에 대한 HuggingFace 문서는 [이곳](https://huggingface.co/docs/transformers/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)에서 확인할 수 있습니다.)
+
+
+```python
+from transformers import DbrxForCausalLM, AutoTokenizer
+import torch
+
+tokenizer = AutoTokenizer.from_pretrained("databricks/dbrx-instruct", token="YOUR_HF_TOKEN")
+model = DbrxForCausalLM.from_pretrained(
+ "databricks/dbrx-instruct",
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+ token="YOUR_HF_TOKEN",
+ attn_implementation="sdpa",
+ )
+
+input_text = "What does it take to build a great LLM?"
+messages = [{"role": "user", "content": input_text}]
+input_ids = tokenizer.apply_chat_template(messages, return_dict=True, tokenize=True, add_generation_prompt=True, return_tensors="pt").to("cuda")
+
+outputs = model.generate(**input_ids, max_new_tokens=200)
+print(tokenizer.decode(outputs[0]))
+```
+
+## DbrxConfig[[transformers.DbrxConfig]]
+
+[[autodoc]] DbrxConfig
+
+
+## DbrxModel[[transformers.DbrxModel]]
+
+[[autodoc]] DbrxModel
+ - forward
+
+
+## DbrxForCausalLM[[transformers.DbrxForCausalLM]]
+
+[[autodoc]] DbrxForCausalLM
+ - forward
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/deberta-v2.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/deberta-v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..2e590ad8a5abcf90da995dc90b6592c8a205b309
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/deberta-v2.md
@@ -0,0 +1,147 @@
+
+
+# DeBERTa-v2
+
+## 개요
+
+
+DeBERTa 모델은 Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen이 작성한 [DeBERTa: 분리된 어텐션을 활용한 디코딩 강화 BERT](https://arxiv.org/abs/2006.03654)이라는 논문에서 제안되었습니다. 이 모델은 2018년 Google이 발표한 BERT 모델과 2019년 Facebook이 발표한 RoBERTa 모델을 기반으로 합니다.
+DeBERTa는 RoBERTa에서 사용된 데이터의 절반만을 사용하여 분리된(disentangled) 어텐션과 향상된 마스크 디코더 학습을 통해 RoBERTa를 개선했습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*사전 학습된 신경망 언어 모델의 최근 발전은 많은 자연어 처리(NLP) 작업의 성능을 크게 향상시켰습니다. 본 논문에서는 두 가지 새로운 기술을 사용하여 BERT와 RoBERTa 모델을 개선한 새로운 모델 구조인 DeBERTa를 제안합니다. 첫 번째는 분리된 어텐션 메커니즘으로, 각 단어가 내용과 위치를 각각 인코딩하는 두 개의 벡터로 표현되며, 단어들 간의 어텐션 가중치는 내용과 상대적 위치에 대한 분리된 행렬을 사용하여 계산됩니다. 두 번째로, 모델 사전 학습을 위해 마스킹된 토큰을 예측하는 출력 소프트맥스 층을 대체하는 향상된 마스크 디코더가 사용됩니다. 우리는 이 두 가지 기술이 모델 사전 학습의 효율성과 다운스트림 작업의 성능을 크게 향상시킨다는 것을 보여줍니다. RoBERTa-Large와 비교했을 때, 절반의 학습 데이터로 학습된 DeBERTa 모델은 광범위한 NLP 작업에서 일관되게 더 나은 성능을 보여주며, MNLI에서 +0.9%(90.2% vs 91.1%), SQuAD v2.0에서 +2.3%(88.4% vs 90.7%), RACE에서 +3.6%(83.2% vs 86.8%)의 성능 향상을 달성했습니다. DeBERTa 코드와 사전 학습된 모델은 https://github.com/microsoft/DeBERTa 에서 공개될 예정입니다.*
+
+
+다음 정보들은 [원본 구현 저장소](https://github.com/microsoft/DeBERTa)에서 보실 수 있습니다. DeBERTa v2는 DeBERTa의 두번째 모델입니다.
+DeBERTa v2는 SuperGLUE 단일 모델 제출에 사용된 1.5B 모델을 포함하며, 인간 기준점(베이스라인) 89.8점 대비 89.9점을 달성했습니다. 저자의
+[블로그](https://www.microsoft.com/en-us/research/blog/microsoft-deberta-surpasses-human-performance-on-the-superglue-benchmark/)에서 더 자세한 정보를 확인할 수 있습니다.
+
+v2의 새로운 점:
+
+- **어휘(Vocabulary)** v2에서는 학습 데이터로부터 구축된 128K 크기의 새로운 어휘를 사용하도록 토크나이저가 변경되었습니다. GPT2 기반 토크나이저 대신, 이제는 [센텐스피스 기반](https://github.com/google/sentencepiece) 토크나이저를 사용합니다.
+- **nGiE[n그램 유도(Induced) 입력 인코딩]** DeBERTa-v2 모델은 입력 토큰들의 지역적 의존성을 더 잘 학습하기 위해 첫 번째 트랜스포머 층과 함께 추가적인 합성곱 층을 사용합니다.
+- **어텐션 층에서 위치 투영 행렬과 내용 투영 행렬 공유** 이전 실험들을 기반으로, 이는 성능에 영향을 주지 않으면서 매개변수를 절약할 수 있습니다.
+- **상대적 위치를 인코딩하기 위한 버킷 적용** DeBERTa-v2 모델은 T5와 유사하게 상대적 위치를 인코딩하기 위해 로그 버킷을 사용합니다.
+- **900M 모델 & 1.5B 모델** 900M과 1.5B, 두 가지 추가 모델 크기가 제공되며, 이는 다운스트림 작업의 성능을 크게 향상시킵니다.
+
+[DeBERTa](https://huggingface.co/DeBERTa) 모델의 텐서플로 2.0 구현은 [kamalkraj](https://huggingface.co/kamalkraj)가 기여했습니다. 원본 코드는 [이곳](https://github.com/microsoft/DeBERTa)에서 확인하실 수 있습니다.
+
+## 자료
+
+- [텍스트 분류 작업 가이드](../tasks/sequence_classification)
+- [토큰 분류 작업 가이드](../tasks/token_classification)
+- [질의응답 작업 가이드](../tasks/question_answering)
+- [마스크 언어 모델링 작업 가이드](../tasks/masked_language_modeling)
+- [다중 선택 작업 가이드](../tasks/multiple_choice)
+
+## DebertaV2Config
+
+[[autodoc]] DebertaV2Config
+
+## DebertaV2Tokenizer
+
+[[autodoc]] DebertaV2Tokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## DebertaV2TokenizerFast
+
+[[autodoc]] DebertaV2TokenizerFast
+ - build_inputs_with_special_tokens
+ - create_token_type_ids_from_sequences
+
+
+
+
+## DebertaV2Model
+
+[[autodoc]] DebertaV2Model
+ - forward
+
+## DebertaV2PreTrainedModel
+
+[[autodoc]] DebertaV2PreTrainedModel
+ - forward
+
+## DebertaV2ForMaskedLM
+
+[[autodoc]] DebertaV2ForMaskedLM
+ - forward
+
+## DebertaV2ForSequenceClassification
+
+[[autodoc]] DebertaV2ForSequenceClassification
+ - forward
+
+## DebertaV2ForTokenClassification
+
+[[autodoc]] DebertaV2ForTokenClassification
+ - forward
+
+## DebertaV2ForQuestionAnswering
+
+[[autodoc]] DebertaV2ForQuestionAnswering
+ - forward
+
+## DebertaV2ForMultipleChoice
+
+[[autodoc]] DebertaV2ForMultipleChoice
+ - forward
+
+
+
+
+## TFDebertaV2Model
+
+[[autodoc]] TFDebertaV2Model
+ - call
+
+## TFDebertaV2PreTrainedModel
+
+[[autodoc]] TFDebertaV2PreTrainedModel
+ - call
+
+## TFDebertaV2ForMaskedLM
+
+[[autodoc]] TFDebertaV2ForMaskedLM
+ - call
+
+## TFDebertaV2ForSequenceClassification
+
+[[autodoc]] TFDebertaV2ForSequenceClassification
+ - call
+
+## TFDebertaV2ForTokenClassification
+
+[[autodoc]] TFDebertaV2ForTokenClassification
+ - call
+
+## TFDebertaV2ForQuestionAnswering
+
+[[autodoc]] TFDebertaV2ForQuestionAnswering
+ - call
+
+## TFDebertaV2ForMultipleChoice
+
+[[autodoc]] TFDebertaV2ForMultipleChoice
+ - call
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/deberta.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/deberta.md
new file mode 100644
index 0000000000000000000000000000000000000000..6f82bed033a0e063b80210a71325741868fdc994
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/deberta.md
@@ -0,0 +1,152 @@
+
+
+# DeBERTa[[deberta]]
+
+## 개요[[overview]]
+
+
+DeBERTa 모델은 Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen이 작성한 [DeBERTa: 분리된 어텐션을 활용한 디코딩 강화 BERT](https://arxiv.org/abs/2006.03654)이라는 논문에서 제안되었습니다. 이 모델은 2018년 Google이 발표한 BERT 모델과 2019년 Facebook이 발표한 RoBERTa 모델을 기반으로 합니다.
+DeBERTa는 RoBERTa에서 사용된 데이터의 절반만을 사용하여 분리된(disentangled) 어텐션과 향상된 마스크 디코더 학습을 통해 RoBERTa를 개선했습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*사전 학습된 신경망 언어 모델의 최근 발전은 많은 자연어 처리(NLP) 작업의 성능을 크게 향상시켰습니다. 본 논문에서는 두 가지 새로운 기술을 사용하여 BERT와 RoBERTa 모델을 개선한 새로운 모델 구조인 DeBERTa를 제안합니다. 첫 번째는 분리된 어텐션 메커니즘으로, 각 단어가 내용과 위치를 각각 인코딩하는 두 개의 벡터로 표현되며, 단어들 간의 어텐션 가중치는 내용과 상대적 위치에 대한 분리된 행렬을 사용하여 계산됩니다. 두 번째로, 모델 사전 학습을 위해 마스킹된 토큰을 예측하는 출력 소프트맥스 층을 대체하는 향상된 마스크 디코더가 사용됩니다. 우리는 이 두 가지 기술이 모델 사전 학습의 효율성과 다운스트림 작업의 성능을 크게 향상시킨다는 것을 보여줍니다. RoBERTa-Large와 비교했을 때, 절반의 학습 데이터로 학습된 DeBERTa 모델은 광범위한 NLP 작업에서 일관되게 더 나은 성능을 보여주며, MNLI에서 +0.9%(90.2% vs 91.1%), SQuAD v2.0에서 +2.3%(88.4% vs 90.7%), RACE에서 +3.6%(83.2% vs 86.8%)의 성능 향상을 달성했습니다. DeBERTa 코드와 사전 학습된 모델은 https://github.com/microsoft/DeBERTa 에서 공개될 예정입니다.*
+
+[DeBERTa](https://huggingface.co/DeBERTa) 모델의 텐서플로 2.0 구현은 [kamalkraj](https://huggingface.co/kamalkraj)가 기여했습니다. 원본 코드는 [이곳](https://github.com/microsoft/DeBERTa)에서 확인하실 수 있습니다.
+
+## 리소스[[resources]]
+
+
+DeBERTa를 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰해 드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+
+
+
+
+## DebertaModel[[transformers.DebertaModel]]
+
+[[autodoc]] DebertaModel
+ - forward
+
+## DebertaPreTrainedModel[[transformers.DebertaPreTrainedModel]]
+
+[[autodoc]] DebertaPreTrainedModel
+
+## DebertaForMaskedLM[[transformers.DebertaForMaskedLM]]
+
+[[autodoc]] DebertaForMaskedLM
+ - forward
+
+## DebertaForSequenceClassification[[transformers.DebertaForSequenceClassification]]
+
+[[autodoc]] DebertaForSequenceClassification
+ - forward
+
+## DebertaForTokenClassification[[transformers.DebertaForTokenClassification]]
+
+[[autodoc]] DebertaForTokenClassification
+ - forward
+
+## DebertaForQuestionAnswering[[transformers.DebertaForQuestionAnswering]]
+
+[[autodoc]] DebertaForQuestionAnswering
+ - forward
+
+
+
+
+## TFDebertaModel[[transformers.TFDebertaModel]]
+
+[[autodoc]] TFDebertaModel
+ - call
+
+## TFDebertaPreTrainedModel[[transformers.TFDebertaPreTrainedModel]]
+
+[[autodoc]] TFDebertaPreTrainedModel
+ - call
+
+## TFDebertaForMaskedLM[[transformers.TFDebertaForMaskedLM]]
+
+[[autodoc]] TFDebertaForMaskedLM
+ - call
+
+## TFDebertaForSequenceClassification[[transformers.TFDebertaForSequenceClassification]]
+
+[[autodoc]] TFDebertaForSequenceClassification
+ - call
+
+## TFDebertaForTokenClassification[[transformers.TFDebertaForTokenClassification]]
+
+[[autodoc]] TFDebertaForTokenClassification
+ - call
+
+## TFDebertaForQuestionAnswering[[transformers.TFDebertaForQuestionAnswering]]
+
+[[autodoc]] TFDebertaForQuestionAnswering
+ - call
+
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/encoder-decoder.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/encoder-decoder.md
new file mode 100644
index 0000000000000000000000000000000000000000..c5c553561395361bf2ea588f50a5bb3756d213a8
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/encoder-decoder.md
@@ -0,0 +1,167 @@
+
+
+# 인코더-디코더 모델[[Encoder Decoder Models]]
+
+## 개요[[Overview]]
+
+[`EncoderDecoderModel`]은 사전 학습된 자동 인코딩(autoencoding) 모델을 인코더로, 사전 학습된 자가 회귀(autoregressive) 모델을 디코더로 활용하여 시퀀스-투-시퀀스(sequence-to-sequence) 모델을 초기화하는 데 이용됩니다.
+
+사전 학습된 체크포인트를 활용해 시퀀스-투-시퀀스 모델을 초기화하는 것이 시퀀스 생성(sequence generation) 작업에 효과적이라는 점이 Sascha Rothe, Shashi Narayan, Aliaksei Severyn의 논문 [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461)에서 입증되었습니다.
+
+[`EncoderDecoderModel`]이 학습/미세 조정된 후에는 다른 모델과 마찬가지로 저장/불러오기가 가능합니다. 자세한 사용법은 예제를 참고하세요.
+
+이 아키텍처의 한 가지 응용 사례는 두 개의 사전 학습된 [`BertModel`]을 각각 인코더와 디코더로 활용하여 요약 모델(summarization model)을 구축하는 것입니다. 이는 Yang Liu와 Mirella Lapata의 논문 [Text Summarization with Pretrained Encoders](https://arxiv.org/abs/1908.08345)에서 제시된 바 있습니다.
+
+## 모델 설정에서 `EncoderDecoderModel`을 무작위 초기화하기[[Randomly initializing `EncoderDecoderModel` from model configurations.]]
+
+[`EncoderDecoderModel`]은 인코더와 디코더 설정(config)을 기반으로 무작위 초기화를 할 수 있습니다. 아래 예시는 [`BertModel`] 설정을 인코더로, 기본 [`BertForCausalLM`] 설정을 디코더로 사용하는 방법을 보여줍니다.
+
+```python
+>>> from transformers import BertConfig, EncoderDecoderConfig, EncoderDecoderModel
+
+>>> config_encoder = BertConfig()
+>>> config_decoder = BertConfig()
+
+>>> config = EncoderDecoderConfig.from_encoder_decoder_configs(config_encoder, config_decoder)
+>>> model = EncoderDecoderModel(config=config)
+```
+
+## 사전 학습된 인코더와 디코더로 `EncoderDecoderModel` 초기화하기[[Initialising `EncoderDecoderModel` from a pretrained encoder and a pretrained decoder.]]
+
+[`EncoderDecoderModel`]은 사전 학습된 인코더 체크포인트와 사전 학습된 디코더 체크포인트를 사용해 초기화할 수 있습니다. BERT와 같은 모든 사전 학습된 자동 인코딩(auto-encoding) 모델은 인코더로 활용할 수 있으며, GPT2와 같은 자가 회귀(autoregressive) 모델이나 BART의 디코더와 같이 사전 학습된 시퀀스-투-시퀀스 디코더 모델을 디코더로 사용할 수 있습니다. 디코더로 선택한 아키텍처에 따라 교차 어텐션(cross-attention) 레이어가 무작위로 초기화될 수 있습니다. 사전 학습된 인코더와 디코더 체크포인트를 이용해 [`EncoderDecoderModel`]을 초기화하려면, 모델을 다운스트림 작업에 대해 미세 조정(fine-tuning)해야 합니다. 이에 대한 자세한 내용은 [the *Warm-starting-encoder-decoder blog post*](https://huggingface.co/blog/warm-starting-encoder-decoder)에 설명되어 있습니다. 이 작업을 위해 `EncoderDecoderModel` 클래스는 [`EncoderDecoderModel.from_encoder_decoder_pretrained`] 메서드를 제공합니다.
+
+
+```python
+>>> from transformers import EncoderDecoderModel, BertTokenizer
+
+>>> tokenizer = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+>>> model = EncoderDecoderModel.from_encoder_decoder_pretrained("google-bert/bert-base-uncased", "google-bert/bert-base-uncased")
+```
+
+## 기존 `EncoderDecoderModel` 체크포인트 불러오기 및 추론하기[[Loading an existing `EncoderDecoderModel` checkpoint and perform inference.]]
+
+`EncoderDecoderModel` 클래스의 미세 조정(fine-tuned)된 체크포인트를 불러오려면, Transformers의 다른 모델 아키텍처와 마찬가지로 [`EncoderDecoderModel`]에서 제공하는 `from_pretrained(...)`를 사용할 수 있습니다.
+
+추론을 수행하려면 [`generate`] 메서드를 활용하여 텍스트를 자동 회귀(autoregressive) 방식으로 생성할 수 있습니다. 이 메서드는 탐욕 디코딩(greedy decoding), 빔 서치(beam search), 다항 샘플링(multinomial sampling) 등 다양한 디코딩 방식을 지원합니다.
+
+```python
+>>> from transformers import AutoTokenizer, EncoderDecoderModel
+
+>>> # 미세 조정된 seq2seq 모델과 대응하는 토크나이저 가져오기
+>>> model = EncoderDecoderModel.from_pretrained("patrickvonplaten/bert2bert_cnn_daily_mail")
+>>> tokenizer = AutoTokenizer.from_pretrained("patrickvonplaten/bert2bert_cnn_daily_mail")
+
+>>> # let's perform inference on a long piece of text
+>>> ARTICLE_TO_SUMMARIZE = (
+... "PG&E stated it scheduled the blackouts in response to forecasts for high winds "
+... "amid dry conditions. The aim is to reduce the risk of wildfires. Nearly 800 thousand customers were "
+... "scheduled to be affected by the shutoffs which were expected to last through at least midday tomorrow."
+... )
+>>> input_ids = tokenizer(ARTICLE_TO_SUMMARIZE, return_tensors="pt").input_ids
+
+>>> # 자기회귀적으로 요약 생성 (기본적으로 그리디 디코딩 사용)
+>>> generated_ids = model.generate(input_ids)
+>>> generated_text = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+>>> print(generated_text)
+nearly 800 thousand customers were affected by the shutoffs. the aim is to reduce the risk of wildfires. nearly 800, 000 customers were expected to be affected by high winds amid dry conditions. pg & e said it scheduled the blackouts to last through at least midday tomorrow.
+```
+
+## `TFEncoderDecoderModel`에 Pytorch 체크포인트 불러오기[[Loading a PyTorch checkpoint into `TFEncoderDecoderModel`.]]
+
+[`TFEncoderDecoderModel.from_pretrained`] 메서드는 현재 Pytorch 체크포인트를 사용한 모델 초기화를 지원하지 않습니다. 이 메서드에 `from_pt=True`를 전달하면 예외(exception)가 발생합니다. 특정 인코더-디코더 모델에 대한 Pytorch 체크포인트만 존재하는 경우, 다음과 같은 해결 방법을 사용할 수 있습니다:
+
+```python
+>>> # 파이토치 체크포인트에서 로드하는 해결 방법
+>>> from transformers import EncoderDecoderModel, TFEncoderDecoderModel
+
+>>> _model = EncoderDecoderModel.from_pretrained("patrickvonplaten/bert2bert-cnn_dailymail-fp16")
+
+>>> _model.encoder.save_pretrained("./encoder")
+>>> _model.decoder.save_pretrained("./decoder")
+
+>>> model = TFEncoderDecoderModel.from_encoder_decoder_pretrained(
+... "./encoder", "./decoder", encoder_from_pt=True, decoder_from_pt=True
+... )
+>>> # 이 부분은 특정 모델의 구체적인 세부사항을 복사할 때에만 사용합니다.
+>>> model.config = _model.config
+```
+
+## 학습[[Training]]
+
+모델이 생성된 후에는 BART, T5 또는 기타 인코더-디코더 모델과 유사한 방식으로 미세 조정(fine-tuning)할 수 있습니다.
+보시다시피, 손실(loss)을 계산하려면 단 2개의 입력만 필요합니다: `input_ids`(입력 시퀀스를 인코딩한 `input_ids`)와 `labels`(목표 시퀀스를 인코딩한 `input_ids`).
+
+```python
+>>> from transformers import BertTokenizer, EncoderDecoderModel
+
+>>> tokenizer = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+>>> model = EncoderDecoderModel.from_encoder_decoder_pretrained("google-bert/bert-base-uncased", "google-bert/bert-base-uncased")
+
+>>> model.config.decoder_start_token_id = tokenizer.cls_token_id
+>>> model.config.pad_token_id = tokenizer.pad_token_id
+
+>>> input_ids = tokenizer(
+... "The tower is 324 metres (1,063 ft) tall, about the same height as an 81-storey building, and the tallest structure in Paris. Its base is square, measuring 125 metres (410 ft) on each side.During its construction, the Eiffel Tower surpassed the Washington Monument to become the tallest man-made structure in the world, a title it held for 41 years until the Chrysler Building in New York City was finished in 1930. It was the first structure to reach a height of 300 metres. Due to the addition of a broadcasting aerial at the top of the tower in 1957, it is now taller than the Chrysler Building by 5.2 metres (17 ft).Excluding transmitters, the Eiffel Tower is the second tallest free-standing structure in France after the Millau Viaduct.",
+... return_tensors="pt",
+... ).input_ids
+
+>>> labels = tokenizer(
+... "the eiffel tower surpassed the washington monument to become the tallest structure in the world. it was the first structure to reach a height of 300 metres in paris in 1930. it is now taller than the chrysler building by 5. 2 metres ( 17 ft ) and is the second tallest free - standing structure in paris.",
+... return_tensors="pt",
+... ).input_ids
+
+>>> # forward 함수가 자동으로 적합한 decoder_input_ids를 생성합니다.
+>>> loss = model(input_ids=input_ids, labels=labels).loss
+```
+훈련에 대한 자세한 내용은 [colab](https://colab.research.google.com/drive/1WIk2bxglElfZewOHboPFNj8H44_VAyKE?usp=sharing#scrollTo=ZwQIEhKOrJpl) 노트북을 참조하세요.
+
+이 모델은 [thomwolf](https://github.com/thomwolf)가 기여했으며, 이 모델에 대한 TensorFlow 및 Flax 버전은 [ydshieh](https://github.com/ydshieh)가 기여했습니다.
+
+
+## EncoderDecoderConfig
+
+[[autodoc]] EncoderDecoderConfig
+
+
+
+
+## EncoderDecoderModel
+
+[[autodoc]] EncoderDecoderModel
+ - forward
+ - from_encoder_decoder_pretrained
+
+
+
+
+## TFEncoderDecoderModel
+
+[[autodoc]] TFEncoderDecoderModel
+ - call
+ - from_encoder_decoder_pretrained
+
+
+
+
+## FlaxEncoderDecoderModel
+
+[[autodoc]] FlaxEncoderDecoderModel
+ - __call__
+ - from_encoder_decoder_pretrained
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/esm.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/esm.md
new file mode 100644
index 0000000000000000000000000000000000000000..6ea1191dabe0bae8306f981b7bffe9dfd8edbd94
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/esm.md
@@ -0,0 +1,115 @@
+
+
+# ESM [[esm]]
+
+## 개요 [[overview]]
+
+이 페이지는 Meta AI의 Fundamental AI Research 팀에서 제공하는 Transformer 단백질 언어 모델에 대한 코드와 사전 훈련된 가중치를 제공합니다. 여기에는 최첨단인 ESMFold와 ESM-2, 그리고 이전에 공개된 ESM-1b와 ESM-1v가 포함됩니다. Transformer 단백질 언어 모델은 Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott, C. Lawrence Zitnick, Jerry Ma, Rob Fergus의 논문 [Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118)에서 소개되었습니다. 이 논문의 첫 번째 버전은 2019년에 [출판 전 논문](https://www.biorxiv.org/content/10.1101/622803v1?versioned=true) 형태로 공개되었습니다.
+
+ESM-2는 다양한 구조 예측 작업에서 테스트된 모든 단일 시퀀스 단백질 언어 모델을 능가하며, 원자 수준의 구조 예측을 가능하게 합니다. 이 모델은 Zeming Lin, Halil Akin, Roshan Rao, Brian Hie, Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido, Alexander Rives의 논문 [Language models of protein sequences at the scale of evolution enable accurate structure prediction](https://doi.org/10.1101/2022.07.20.500902)에서 공개되었습니다.
+
+이 논문에서 함께 소개된 ESMFold는 ESM-2 스템을 사용하며, 최첨단의 정확도로 단백질 접힘 구조를 예측할 수 있는 헤드를 갖추고 있습니다. [AlphaFold2](https://www.nature.com/articles/s41586-021-03819-2)와 달리, 이는 대형 사전 훈련된 단백질 언어 모델 스템의 토큰 임베딩에 의존하며, 추론 시 다중 시퀀스 정렬(MSA) 단계를 수행하지 않습니다. 이는 ESMFold 체크포인트가 완전히 "독립적"이며, 예측을 위해 알려진 단백질 시퀀스와 구조의 데이터베이스, 그리고 그와 관련 외부 쿼리 도구를 필요로 하지 않는다는 것을 의미합니다. 그리고 그 결과, 훨씬 빠릅니다.
+
+"Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences"의 초록은 다음과 같습니다:
+
+*인공지능 분야에서는 대규모의 데이터와 모델 용량을 갖춘 비지도 학습의 조합이 표현 학습과 통계적 생성에서 주요한 발전을 이끌어냈습니다. 생명 과학에서는 시퀀싱 기술의 성장이 예상되며, 자연 시퀀스 다양성에 대한 전례 없는 데이터가 나올 것으로 기대됩니다. 진화적 단계에서 볼 때, 단백질 언어 모델링은 생물학을 위한 예측 및 생성 인공지능을 향한 논리적인 단계에 있습니다. 이를 위해 우리는 진화적 다양성을 아우르는 2억 5천만 개의 단백질 시퀀스에서 추출한 860억 개의 아미노산에 대해 심층 컨텍스트 언어 모델을 비지도 학습으로 훈련합니다. 그 결과 모델은 그 표현에서 생물학적 속성에 대한 정보를 포함합니다. 이 표현은 시퀀스 데이터만으로 학습됩니다. 학습된 표현 공간은 아미노산의 생화학적 특성 수준에서부터 단백질의 원거리 상동성까지 구조를 반영하는 다중 규모의 조직을 가지고 있습니다. 이 표현에는 2차 및 3차 구조에 대한 정보가 인코딩되어 있으며, 선형 전사에 의해 식별 될 수 있습니다. 표현 학습은 돌연변이에 의한 효과와 2차 구조의 최첨단 지도 예측을 가능하게 하고, 넓은 범위의 접촉 부위 예측을 위한 최첨단 특징을 향상시킵니다.*
+
+"Language models of protein sequences at the scale of evolution enable accurate structure prediction"의 초록은 다음과 같습니다:
+
+*대형 언어 모델은 최근 규모가 커짐에 따라 긴급한 기능을 개발하여 단순한 패턴 매칭을 넘어 더 높은 수준의 추론을 수행하고 생생한 이미지와 텍스트를 생성하는 것으로 나타났습니다. 더 작은 규모에서 훈련된 단백질 시퀀스의 언어 모델이 연구되었지만, 그들이 규모가 커짐에 따라 생물학에 대해 무엇을 배우는지는 거의 알려져 있지 않습니다. 이 연구에서 우리는 현재까지 평가된 가장 큰 150억 개의 매개변수를 가진 모델을 훈련합니다. 우리는 모델이 규모가 커짐에 따라 단일 아미노산의 해상도로 단백질의 3차원 구조를 예측할 수 있는 정보를 학습한다는 것을 발견했습니다. 우리는 개별 단백질 시퀀스로부터 직접 고정밀 원자 수준의 엔드-투-엔드 구조 예측을 하기 위한 ESMFold를 제시합니다. ESMFold는 언어 모델에 잘 이해되는 낮은 퍼플렉서티를 가진 시퀀스에 대해 AlphaFold2와 RoseTTAFold와 유사한 정확도를 가지고 있습니다. ESMFold의 추론은 AlphaFold2보다 한 자릿수 빠르며, 메타게놈 단백질의 구조적 공간을 실용적인 시간 내에 탐색할 수 있게 합니다.*
+
+원본 코드는 [여기](https://github.com/facebookresearch/esm)에서 찾을 수 있으며, Meta AI의 Fundamental AI Research 팀에서 개발되었습니다. ESM-1b, ESM-1v, ESM-2는 [jasonliu](https://huggingface.co/jasonliu)와 [Matt](https://huggingface.co/Rocketknight1)에 의해 HuggingFace에 기여되었습니다.
+
+ESMFold는 [Matt](https://huggingface.co/Rocketknight1)와 [Sylvain](https://huggingface.co/sgugger)에 의해 HuggingFace에 기여되었으며, 이 과정에서 많은 도움을 준 Nikita Smetanin, Roshan Rao, Tom Sercu에게 큰 감사를 드립니다!
+
+## 사용 팁 [[usage-tips]]
+
+- ESM 모델은 마스크드 언어 모델링(MLM) 목표로 훈련되었습니다.
+- HuggingFace의 ESMFold 포트는 [openfold](https://github.com/aqlaboratory/openfold) 라이브러리의 일부를 사용합니다. `openfold` 라이브러리는 Apache License 2.0에 따라 라이선스가 부여됩니다.
+
+## 리소스 [[resources]]
+
+- [텍스트 분류 작업 가이드](../tasks/sequence_classification)
+- [토큰 분류 작업 가이드](../tasks/token_classification)
+- [마스킹드 언어 모델링 작업 가이드](../tasks/masked_language_modeling)
+
+## EsmConfig [[transformers.EsmConfig]]
+
+[[autodoc]] EsmConfig
+ - all
+
+## EsmTokenizer [[transformers.EsmTokenizer]]
+
+[[autodoc]] EsmTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+
+
+
+## EsmModel [[transformers.EsmModel]]
+
+[[autodoc]] EsmModel
+ - forward
+
+## EsmForMaskedLM [[transformers.EsmForMaskedLM]]
+
+[[autodoc]] EsmForMaskedLM
+ - forward
+
+## EsmForSequenceClassification [[transformers.EsmForSequenceClassification]]
+
+[[autodoc]] EsmForSequenceClassification
+ - forward
+
+## EsmForTokenClassification [[transformers.EsmForTokenClassification]]
+
+[[autodoc]] EsmForTokenClassification
+ - forward
+
+## EsmForProteinFolding [[transformers.EsmForProteinFolding]]
+
+[[autodoc]] EsmForProteinFolding
+ - forward
+
+
+
+
+## TFEsmModel [[transformers.TFEsmModel]]
+
+[[autodoc]] TFEsmModel
+ - call
+
+## TFEsmForMaskedLM [[transformers.TFEsmForMaskedLM]]
+
+[[autodoc]] TFEsmForMaskedLM
+ - call
+
+## TFEsmForSequenceClassification [[transformers.TFEsmForSequenceClassification]]
+
+[[autodoc]] TFEsmForSequenceClassification
+ - call
+
+## TFEsmForTokenClassification [[transformers.TFEsmForTokenClassification]]
+
+[[autodoc]] TFEsmForTokenClassification
+ - call
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/gemma.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/gemma.md
new file mode 100644
index 0000000000000000000000000000000000000000..25fe6f1c772950ec5bab3d0f3a9850666d90b94f
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/gemma.md
@@ -0,0 +1,76 @@
+
+
+# Gemma [[gemma]]
+
+## 개요 [[overview]]
+
+Gemma 모델은 Google의 Gemma 팀이 작성한 [Gemma: Open Models Based on Gemini Technology and Research](https://blog.google/technology/developers/gemma-open-models/)에서 제안되었습니다.
+
+Gemma 모델은 6조 토큰으로 학습되었으며, 2b와 7b의 두 가지 버전으로 출시되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*이 연구는 언어 이해, 추론 및 안전성에 대한 학술 벤치마크에서 뛰어난 성능을 보이는 새로운 오픈 언어 모델 계열인 Gemma를 소개합니다. 우리는 두 가지 크기(20억 및 70억 매개변수)의 모델을 출시하며, 사전 학습된 체크포인트와 미세 조정된 체크포인트를 모두 제공합니다. Gemma는 18개의 텍스트 기반 작업 중 11개에서 유사한 크기의 오픈 모델을 능가하며, 우리는 모델 개발에 대한 상세한 설명과 함께 안전성과 책임 측면에 대한 종합적인 평가를 제공합니다. 우리는 LLM의 책임감 있는 공개가 최첨단 모델의 안전성을 향상시키고 다음 세대의 LLM 혁신을 가능하게 하는 데 중요하다고 믿습니다.*
+
+팁:
+
+- 원본 체크포인트는 변환 스크립트 `src/transformers/models/gemma/convert_gemma_weights_to_hf.py`를 사용하여 변환할 수 있습니다.
+
+이 모델은 [Arthur Zucker](https://huggingface.co/ArthurZ), [Younes Belkada](https://huggingface.co/ybelkada), [Sanchit Gandhi](https://huggingface.co/sanchit-gandhi), [Pedro Cuenca](https://huggingface.co/pcuenq)가 기여했습니다.
+
+## GemmaConfig [[transformers.GemmaConfig]]
+
+[[autodoc]] GemmaConfig
+
+## GemmaTokenizer [[transformers.GemmaTokenizer]]
+
+[[autodoc]] GemmaTokenizer
+
+
+## GemmaTokenizerFast [[transformers.GemmaTokenizerFast]]
+
+[[autodoc]] GemmaTokenizerFast
+
+## GemmaModel [[transformers.GemmaModel]]
+
+[[autodoc]] GemmaModel
+ - forward
+
+## GemmaForCausalLM [[transformers.GemmaForCausalLM]]
+
+[[autodoc]] GemmaForCausalLM
+ - forward
+
+## GemmaForSequenceClassification [[transformers.GemmaForSequenceClassification]]
+
+[[autodoc]] GemmaForSequenceClassification
+ - forward
+
+## GemmaForTokenClassification [[transformers.GemmaForTokenClassification]]
+
+[[autodoc]] GemmaForTokenClassification
+ - forward
+
+## FlaxGemmaModel [[transformers.FlaxGemmaModel]]
+
+[[autodoc]] FlaxGemmaModel
+ - __call__
+
+## FlaxGemmaForCausalLM [[transformers.FlaxGemmaForCausalLM]]
+
+[[autodoc]] FlaxGemmaForCausalLM
+ - __call__
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/gemma2.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/gemma2.md
new file mode 100644
index 0000000000000000000000000000000000000000..6bffec616c6e97d853a8e4d0b8f279bf1033d668
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/gemma2.md
@@ -0,0 +1,63 @@
+
+
+
+# Gemma2 [[gemma2]]
+
+## 개요 [[overview]]
+
+Gemma2 모델은 Google의 Gemma2 팀이 작성한 [Gemma2: Open Models Based on Gemini Technology and Research](https://blog.google/technology/developers/google-gemma-2/)에서 제안되었습니다.
+파라미터 크기가 각각 90억(9B)과 270억(27B)인 두 가지 Gemma2 모델이 출시되었습니다.
+
+블로그 게시물의 초록은 다음과 같습니다:
+
+*이제 우리는 전 세계의 연구자와 개발자들에게 Gemma 2를 공식적으로 출시합니다. 90억(9B)과 270억(27B) 파라미터 크기로 제공되는 Gemma 2는 1세대보다 더 높은 성능과 추론 효율성을 제공하며, 상당한 안전성 향상을 포함하고 있습니다. 사실 270억 규모의 모델은 크기가 두 배 이상인 모델과 비교해도 경쟁력 있는 대안을 제공하며, 이는 작년 12월까지만 해도 독점 모델에서만 가능했던 성능을 제공합니다.*
+
+팁:
+
+- 원본 체크포인트는 변환 스크립트 `src/transformers/models/Gemma2/convert_Gemma2_weights_to_hf.py`를 사용하여 변환할 수 있습니다.
+
+
+
+- Gemma2는 매 두 번째 레이어마다 슬라이딩 윈도우 어텐션을 사용하므로 [`~DynamicCache`] 또는 텐서의 튜플과 같은 일반적인 kv 캐싱에는 적합하지 않습니다. Gemma2의 forward 호출에서 캐싱을 활성화하려면 [`~HybridCache`] 인스턴스를 초기화하고 이를 `past_key_values`로 forward 호출에 전달해야 합니다. 또한 `past_key_values`에 이미 이전의 키와 값이 포함되어 있다면 `cache_position`도 준비해야 합니다.
+
+
+
+이 모델은 [Arthur Zucker](https://huggingface.co/ArthurZ), [Pedro Cuenca](https://huggingface.co/pcuenq), [Tom Arsen]()이 기여했습니다.
+
+## Gemma2Config [[transformers.Gemma2Config]]
+
+[[autodoc]] Gemma2Config
+
+## Gemma2Model [[transformers.Gemma2Model]]
+
+[[autodoc]] Gemma2Model
+ - forward
+
+## Gemma2ForCausalLM [[transformers.Gemma2ForCausalLM]]
+
+[[autodoc]] Gemma2ForCausalLM
+ - forward
+
+## Gemma2ForSequenceClassification [[transformers.Gemma2ForSequenceClassification]]
+
+[[autodoc]] Gemma2ForSequenceClassification
+ - forward
+
+## Gemma2ForTokenClassification [[transformers.Gemma2ForTokenClassification]]
+
+[[autodoc]] Gemma2ForTokenClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/gpt_neox_japanese.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/gpt_neox_japanese.md
new file mode 100644
index 0000000000000000000000000000000000000000..13fb656dd50e9463740e1ea273bfcb9073ecd1e1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/gpt_neox_japanese.md
@@ -0,0 +1,76 @@
+
+
+# GPT-NeoX-Japanese [[gpt-neox-japanese]]
+
+## 개요 [[overview]]
+
+
+일본어를 위한 자동회귀 언어 모델인 GPT-NeoX-Japanese를 소개합니다. 이 모델은 [https://github.com/EleutherAI/gpt-neox](https://github.com/EleutherAI/gpt-neox)에서 학습되었습니다. 일본어는 많은 어휘와 히라가나, 가타카나, 한자의 조합으로 이루어진 독특한 언어입니다. 이러한 일본어의 독특한 구조를 해결하기 위해 [특수 서브워드 토크나이저](https://github.com/tanreinama/Japanese-BPEEncoder_V2)를 사용했습니다. 이 유용한 토크나이저를 오픈소스로 제공해 준 *tanreinama*에게 매우 감사드립니다.
+
+이 모델은 Google의 [PaLM](https://ai.googleblog.com/2022/04/pathways-language-model-palm-scaling-to.html) 연구 권장 사항을 따르며, 트랜스포머 블록에서 편향 파라미터를 제거하여 모델 성능을 향상시켰습니다. 자세한 내용은 [이 기사](https://medium.com/ml-abeja/training-a-better-gpt-2-93b157662ae4)를 참조하세요.
+
+모델 개발은 [ABEJA, Inc.](https://www.abejainc.com/)의 [신야 오타니](https://github.com/SO0529), [타카요시 마카베](https://github.com/spider-man-tm), [안주 아로라](https://github.com/Anuj040), [쿄 하토리](https://github.com/go5paopao)에 의해 주도되었습니다. 이 모델 개발 활동에 대한 자세한 내용은 [여기](https://tech-blog.abeja.asia/entry/abeja-gpt-project-202207)를 참조하세요.
+
+
+
+### 사용 예시 [[usage-example]]
+
+`generate()` 메서드를 사용하면 GPT NeoX Japanese 모델을 통해 텍스트를 생성할 수 있습니다.
+
+```python
+>>> from transformers import GPTNeoXJapaneseForCausalLM, GPTNeoXJapaneseTokenizer
+
+>>> model = GPTNeoXJapaneseForCausalLM.from_pretrained("abeja/gpt-neox-japanese-2.7b")
+>>> tokenizer = GPTNeoXJapaneseTokenizer.from_pretrained("abeja/gpt-neox-japanese-2.7b")
+
+>>> prompt = "人とAIが協調するためには、"
+
+>>> input_ids = tokenizer(prompt, return_tensors="pt").input_ids
+
+>>> gen_tokens = model.generate(
+... input_ids,
+... do_sample=True,
+... temperature=0.9,
+... max_length=100,
+... )
+>>> gen_text = tokenizer.batch_decode(gen_tokens, skip_special_tokens=True)[0]
+
+>>> print(gen_text)
+人とAIが協調するためには、AIと人が共存し、AIを正しく理解する必要があります。
+```
+
+## 자료 [[resources]]
+
+- [일상 언어 모델링 작업 가이드 ](../tasks/language_modeling)
+
+## GPTNeoXJapanese 설정 (GPTNeoXJapaneseConfig) [[transformers.GPTNeoXJapaneseConfig]]
+
+[[autodoc]] GPTNeoXJapaneseConfig
+
+## GPTNeoXJapanese토큰화 (GPTNeoXJapaneseTokenizer) [[transformers.GPTNeoXJapaneseTokenizer]]
+
+[[autodoc]] GPTNeoXJapaneseTokenizer
+
+## GPTNeoXJapaneseModel [[transformers.GPTNeoXJapaneseModel]]
+
+[[autodoc]] GPTNeoXJapaneseModel
+ - forward
+
+## 일상 LLM 을 위한 GPTNeoXJapanese(GPTNeoXJapaneseForCausalLM) [[transformers.GPTNeoXJapaneseForCausalLM]]
+
+[[autodoc]] GPTNeoXJapaneseForCausalLM
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/graphormer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/graphormer.md
new file mode 100644
index 0000000000000000000000000000000000000000..fc6aa2c9e2f7eef354a1ae4835f12d1a883f4938
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/graphormer.md
@@ -0,0 +1,52 @@
+
+
+# Graphormer[[graphormer]]
+
+
+
+이 모델은 유지 보수 모드로만 운영되며, 코드를 변경하는 새로운 PR(Pull Request)은 받지 않습니다.
+이 모델을 실행하는 데 문제가 발생한다면, 이 모델을 지원하는 마지막 버전인 v4.40.2를 다시 설치해 주세요. 다음 명령어를 실행하여 재설치할 수 있습니다: `pip install -U transformers==4.40.2`.
+
+
+
+## 개요[[overview]]
+
+Graphormer 모델은 Chengxuan Ying, Tianle Cai, Shengjie Luo, Shuxin Zheng, Guolin Ke, Di He, Yanming Shen, Tie-Yan Liu가 제안한 [트랜스포머가 그래프 표현에 있어서 정말 약할까?](https://arxiv.org/abs/2106.05234) 라는 논문에서 소개되었습니다. Graphormer는 그래프 트랜스포머 모델입니다. 텍스트 시퀀스 대신 그래프에서 계산을 수행할 수 있도록 수정되었으며, 전처리와 병합 과정에서 임베딩과 관심 특성을 생성한 후 수정된 어텐션을 사용합니다.
+
+해당 논문의 초록입니다:
+
+*트랜스포머 아키텍처는 자연어 처리와 컴퓨터 비전 등 많은 분야에서 지배적인 선택을 받고 있는 아키텍처 입니다. 그러나 그래프 수준 예측 리더보드 상에서는 주류 GNN 변형모델들에 비해 경쟁력 있는 성능을 달성하지 못했습니다. 따라서 트랜스포머가 그래프 표현 학습에서 어떻게 잘 수행될 수 있을지는 여전히 미스터리였습니다. 본 논문에서는 Graphormer를 제시함으로써 이 미스터리를 해결합니다. Graphormer는 표준 트랜스포머 아키텍처를 기반으로 구축되었으며, 특히 최근의 OpenGraphBenchmark Large-Scale Challenge(OGB-LSC)의 광범위한 그래프 표현 학습 작업에서 탁월한 결과를 얻을 수 있었습니다. 그래프에서 트랜스포머를 활용하는데 핵심은 그래프의 구조적 정보를 모델에 효과적으로 인코딩하는 것입니다. 이를 위해 우리는 Graphormer가 그래프 구조 데이터를 더 잘 모델링할 수 있도록 돕는 몇 가지 간단하면서도 효과적인 구조적 인코딩 방법을 제안합니다. 또한, 우리는 Graphormer의 표현을 수학적으로 특성화하고, 그래프의 구조적 정보를 인코딩하는 우리의 방식으로 많은 인기 있는 GNN 변형모델들이 Graphormer의 특수한 경우로 포함될 수 있음을 보여줍니다.*
+
+이 모델은 [clefourrier](https://huggingface.co/clefourrier)가 기여했습니다. 원본 코드는 [이곳](https://github.com/microsoft/Graphormer)에서 확인할 수 있습니다.
+
+## 사용 팁[[usage-tips]]
+
+이 모델은 큰 그래프(100개 이상의 노드개수/엣지개수)에서는 메모리 사용량이 폭발적으로 증가하므로 잘 작동하지 않습니다. 대안으로 배치 크기를 줄이거나, RAM을 늘리거나 또는 algos_graphormer.pyx 파일의 `UNREACHABLE_NODE_DISTANCE` 매개변수를 줄이는 방법도 있지만, 700개 이상의 노드개수/엣지개수를 처리하기에는 여전히 어려울 것입니다.
+
+이 모델은 토크나이저를 사용하지 않고, 대신 훈련 중에 특별한 콜레이터(collator)를 사용합니다.
+
+## GraphormerConfig[[transformers.GraphormerConfig]]
+
+[[autodoc]] GraphormerConfig
+
+## GraphormerModel[[transformers.GraphormerModel]]
+
+[[autodoc]] GraphormerModel
+ - forward
+
+## GraphormerForGraphClassification[[transformers.GraphormerForGraphClassification]]
+
+[[autodoc]] GraphormerForGraphClassification
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/informer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/informer.md
new file mode 100644
index 0000000000000000000000000000000000000000..03722545a5625e7340eedb4a64948d366d190fa4
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/informer.md
@@ -0,0 +1,55 @@
+
+
+# Informer[[informer]]
+
+## 개요[[overview]]
+
+The Informer 모델은 Haoyi Zhou, Shanghang Zhang, Jieqi Peng, Shuai Zhang, Jianxin Li, Hui Xiong, Wancai Zhang가 제안한 [Informer: 장기 시퀀스 시계열 예측(LSTF)을 위한 더욱 효율적인 트랜스포머(Beyond Efficient Transformer)](https://arxiv.org/abs/2012.07436)라는 논문에서 소개되었습니다.
+
+이 방법은 확률적 어텐션 메커니즘을 도입하여 "게으른" 쿼리가 아닌 "활성" 쿼리를 선택하고, 희소 트랜스포머를 제공하여 기존 어텐션의 이차적 계산 및 메모리 요구사항을 완화합니다.
+
+해당 논문의 초록입니다:
+
+*실제로 많은 응용프로그램에서는 장기 시퀀스 시계열 예측(LSTF)을 필요로 합니다. LSTF는 출력 - 입력 간 정확한 장기 의존성 결합도를 포착해내는 높은 예측 능력을 모델에 요구합니다. 최근 연구들은 예측 능력을 향상시킬 수 있는 트랜스포머의 잠재력을 보여주고 있습니다. 그러나, 트랜스포머를 LSTF에 직접 적용하지 못하도록 막는 몇 심각한 문제점들이 있습니다. 예로, 이차 시간 복잡도, 높은 메모리 사용량, 인코더-디코더 아키텍처의 본질적 한계를 들 수 있습니다. 이러한 문제를 해결하기 위해 LSTF를 위한 효율적인 트랜스포머 기반 모델인 Informer를 설계했습니다.
+
+Informer의 세가지 독특한 특성:
+(i) ProbSparse 셀프 어텐션 메커니즘으로, 시간 복잡도와 메모리 사용량에서 O(L logL)를 달성하며 시퀀스 의존성 정렬에서 비교 가능한 성능을 보입니다.
+(ii) 셀프 어텐션 증류는 계단식 레이어 입력을 반으로 줄여 지배적인 어텐션을 강조하고 극단적으로 긴 입력 시퀀스를 효율적으로 처리합니다.
+(iii) 생성 스타일 디코더는 개념적으로 단순하지만 장기 시계열 시퀀스를 단계별 방식이 아닌 한 번의 전방 연산으로 예측하여 장기 시퀀스 예측의 추론 속도를 크게 향상시킵니다. 4개의 대규모 데이터셋에 걸친 광범위한 실험은 Informer가 기존 방법들을 크게 능가하며 LSTF 문제에 새로운 해결책을 제공함을 보여줍니다.*
+
+이 모델은 [elisim](https://huggingface.co/elisim)와 [kashif](https://huggingface.co/kashif)가 기여했습니다.
+원본 코드는 [이곳](https://github.com/zhouhaoyi/Informer2020)에서 확인할 수 있습니다.
+
+## 자료[[resources]]
+
+시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+- HuggingFace 블로그에서 Informer 포스트를 확인하세요: [Informer를 활용한 다변량 확률적 시계열 예측](https://huggingface.co/blog/informer)
+
+## InformerConfig[[transformers.InformerConfig]]
+
+[[autodoc]] InformerConfig
+
+## InformerModel[[transformers.InformerModel]]
+
+[[autodoc]] InformerModel
+ - forward
+
+## InformerForPrediction[[transformers.InformerForPrediction]]
+
+[[autodoc]] InformerForPrediction
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/llama.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/llama.md
new file mode 100644
index 0000000000000000000000000000000000000000..282befac213ddd24d7869bc3438bd3b88959f050
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/llama.md
@@ -0,0 +1,117 @@
+
+
+# LLaMA [[llama]]
+
+## 개요 [[overview]]
+
+LLaMA 모델은 Hugo Touvron, Thibaut Lavril, Gautier Izacard, Xavier Martinet, Marie-Anne Lachaux, Timothée Lacroix, Baptiste Rozière, Naman Goyal, Eric Hambro, Faisal Azhar, Aurelien Rodriguez, Armand Joulin, Edouard Grave, Guillaume Lample에 의해 제안된 [LLaMA: Open and Efficient Foundation Language Models](https://arxiv.org/abs/2302.13971)에서 소개되었습니다. 이 모델은 7B에서 65B개의 파라미터까지 다양한 크기의 기초 언어 모델을 모아놓은 것입니다.
+
+논문의 초록은 다음과 같습니다:
+
+*"LLaMA는 7B에서 65B개의 파라미터 수를 가진 기초 언어 모델의 모음입니다. 우리는 수조 개의 토큰으로 모델을 훈련시켰고, 공개적으로 이용 가능한 데이터셋만을 사용하여 최고 수준의 모델을 훈련시킬 수 있음을 보여줍니다. 특히, LLaMA-13B 모델은 대부분의 벤치마크에서 GPT-3 (175B)를 능가하며, LLaMA-65B는 최고 수준의 모델인 Chinchilla-70B와 PaLM-540B에 버금가는 성능을 보입니다. 우리는 모든 모델을 연구 커뮤니티에 공개합니다."*
+
+팁:
+
+- LLaMA 모델의 가중치는 [이 양식](https://docs.google.com/forms/d/e/1FAIpQLSfqNECQnMkycAp2jP4Z9TFX0cGR4uf7b_fBxjY_OjhJILlKGA/viewform?usp=send_form)을 작성하여 얻을 수 있습니다.
+- 가중치를 다운로드한 후에는 이를 [변환 스크립트](https://github.com/huggingface/transformers/blob/main/src/transformers/models/llama/convert_llama_weights_to_hf.py)를 사용하여 Hugging Face Transformers 형식으로 변환해야합니다. 변환 스크립트를 실행하려면 아래의 예시 명령어를 참고하세요:
+
+```bash
+python src/transformers/models/llama/convert_llama_weights_to_hf.py \
+ --input_dir /path/to/downloaded/llama/weights --model_size 7B --output_dir /output/path
+```
+
+- 변환을 하였다면 모델과 토크나이저는 다음과 같이 로드할 수 있습니다:
+
+```python
+from transformers import LlamaForCausalLM, LlamaTokenizer
+
+tokenizer = LlamaTokenizer.from_pretrained("/output/path")
+model = LlamaForCausalLM.from_pretrained("/output/path")
+```
+
+스크립트를 실행하기 위해서는 모델을 float16 정밀도로 전부 로드할 수 있을 만큼의 충분한 CPU RAM이 필요합니다. (가장 큰 버전의 모델이 여러 체크포인트로 나뉘어 있더라도, 각 체크포인트는 모델의 각 가중치의 일부를 포함하고 있기 때문에 모든 체크포인트를 RAM에 로드해야 합니다) 65B 모델의 경우, 총 130GB의 RAM이 필요합니다.
+
+
+- LLaMA 토크나이저는 [sentencepiece](https://github.com/google/sentencepiece)를 기반으로 하는 BPE 모델입니다. sentencepiece의 특징 중 하나는 시퀀스를 디코딩할 때 첫 토큰이 단어의 시작이라면 (예를 들어 "Banana"), 토크나이저는 문자열 앞에 공백을 추가하지 않는다는 것입니다.
+
+이 모델은 [BlackSamorez](https://huggingface.co/BlackSamorez)의 기여와 함께, [zphang](https://huggingface.co/zphang)에 의해 제공되었습니다. Hugging Face에서의 구현 코드는 GPT-NeoX를 기반으로 하며 [여기](https://github.com/EleutherAI/gpt-neox)에서 찾을 수 있고, 저자의 코드 원본은 [여기](https://github.com/facebookresearch/llama)에서 확인할 수 있습니다.
+
+
+원래 LLaMA 모델을 기반으로 Meta AI에서 몇 가지 후속 작업을 발표했습니다:
+
+- **Llama2**: Llama2는 구조적인 몇 가지 수정(Grouped Query Attention)을 통해 개선된 버전이며, 2조 개의 토큰으로 사전 훈련이 되어 있습니다. Llama2에 대한 자세한 내용은 [이 문서](llama2)를 참고하세요.
+
+## 리소스 [[resources]]
+
+LLaMA를 시작하는 데 도움이 될 Hugging Face 및 커뮤니티(🌎로 표시)의 공식 자료 목록입니다. 여기에 자료를 제출하고 싶다면 Pull Request를 올려주세요! 추가할 자료는 기존의 자료와 중복되지 않고 새로운 내용을 보여주는 것이 좋습니다.
+
+
+
+`Llama2` 모델은 `bfloat16`을 사용하여 훈련되었지만, 원래 추론은 `float16`을 사용합니다. 허브에 업로드된 체크포인트는 `torch_dtype = 'float16'`을 사용하며, 이는 `AutoModel` API에 의해 체크포인트를 `torch.float32`에서 `torch.float16`으로 캐스팅하는 데 사용됩니다.
+
+온라인 가중치의 `dtype`은 `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`를 사용하여 모델을 초기화할 때 `torch_dtype="auto"`를 사용하지 않는 한 대부분 관련이 없습니다. 그 이유는 모델이 먼저 다운로드될 것이고 (온라인 체크포인트의 `dtype`을 사용하여) 그다음에 기본 `dtype`인 `torch`로 캐스팅하고(`torch.float32`가 됨), 마지막으로 구성(configuration)에서 제공된 `torch_dtype`이 있는 경우 이를 사용하기 때문입니다.
+
+모델을 `float16`에서 훈련하는 것은 권장되지 않으며 `nan`을 생성하는 것으로 알려져 있습니다. 따라서 모델은 `bfloat16`에서 훈련되어야 합니다.
+
+
+
+🍯 팁:
+
+- Llama2 모델의 가중치는 [이 양식](https://ai.meta.com/resources/models-and-libraries/llama-downloads/)을 작성하여 얻을 수 있습니다.
+- 아키텍처는 처음 버전의 Llama와 매우 유사하며, [이 논문](https://arxiv.org/pdf/2305.13245.pdf)의 내용에 따라 Grouped Query Attention (GQA)이 추가되었습니다.
+- `config.pretraining_tp`를 1과 다른 값으로 설정하면 더 정확하지만 느린 선형 레이어 계산이 활성화되어 원본 로짓과 더 잘 일치하게 됩니다.
+- 원래 모델은 `pad_id = -1`을 사용하는데, 이는 패딩 토큰이 없음을 의미합니다. 동일한 로직을 사용할 수 없으므로 `tokenizer.add_special_tokens({"pad_token":""})`를 사용하여 패딩 토큰을 추가하고 이에 따라 토큰 임베딩 크기를 조정해야 합니다. 또한 `model.config.pad_token_id`를 설정해야 합니다. 모델의 `embed_tokens` 레이어는 `self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.config.padding_idx)`로 초기화되어, 패딩 토큰 인코딩이 0을 출력하도록 합니다. 따라서 초기화 시에 전달하는 것을 권장합니다.
+- 양식을 작성하고 모델 체크포인트 접근 권한을 얻은 후에는 이미 변환된 체크포인트를 사용할 수 있습니다. 그렇지 않고 자신의 모델을 직접 변환하려는 경우, [변환 스크립트](https://github.com/huggingface/transformers/blob/main/src/transformers/models/llama/convert_llama_weights_to_hf.py)를 자유롭게 사용하세요. 스크립트는 다음과 같은 예시의 명령어로 호출할 수 있습니다:
+
+```bash
+python src/transformers/models/llama/convert_llama_weights_to_hf.py \
+ --input_dir /path/to/downloaded/llama/weights --model_size 7B --output_dir /output/path
+```
+
+- 변환 후 모델과 토크나이저는 다음과 같이 로드할 수 있습니다:
+
+```python
+from transformers import LlamaForCausalLM, LlamaTokenizer
+
+tokenizer = LlamaTokenizer.from_pretrained("/output/path")
+model = LlamaForCausalLM.from_pretrained("/output/path")
+```
+
+스크립트를 실행하려면 모델을 float16 정밀도로 전부 호스트할 수 있을 만큼 충분한 CPU RAM이 필요합니다 (가장 큰 버전이 여러 체크포인트로 제공되더라도 각 체크포인트는 모델 가중치의 일부만을 포함하므로 모두 RAM에 로드해야 합니다). 75B 모델의 경우, 총 145GB의 RAM이 필요합니다.
+
+- LLaMA 토크나이저는 [sentencepiece](https://github.com/google/sentencepiece)를 기반으로 한 BPE 모델입니다. sentencepiece의 특징 중 하나는 시퀀스를 디코딩할 때 첫 번째 토큰이 단어의 시작이면 (예: "Banana") 토크나이저는 문자열 앞에 접두사 공간을 추가하지 않는 것입니다.
+
+이 모델은 [Arthur Zucker](https://huggingface.co/ArthurZ)가 [Lysandre Debut](https://huggingface.co/lysandre)의 도움을 받아 제공하였습니다. Hugging Face에서의 구현 코드는 [여기](https://github.com/EleutherAI/gpt-neox)의 GPT-NeoX 를 기반으로 합니다. 저자의 원래 코드는 [여기](https://github.com/facebookresearch/llama)에서 찾을 수 있습니다.
+
+## 리소스 [[resources]]
+
+LLaMA2를 시작하는 데 도움이 될 Hugging Face의 공식 및 커뮤니티(🌎로 표시) 리소스 목록입니다. 여기에 새로운 리소스를 추가하기 위해서 Pull Request를 열어 주시면 검토하겠습니다! 리소스는 기존 리소스와 중복되지 않는 새로운 것을 보여주는 것이 이상적입니다.
+
+- [Llama 2 is here - get it on Hugging Face](https://huggingface.co/blog/llama2), Llama 2에 관한 블로그 포스트와 🤗 Transformers 및 🤗 PEFT와 함께 사용하는 방법에 대한 내용입니다.
+- [LLaMA 2 - Every Resource you need](https://www.philschmid.de/llama-2), LLaMA 2에 대해 알아보고 빠르게 시작하는 데 필요한 관련 리소스의 모음입니다.
+
+
+
+`라마3` 모델들은 `bfloat16`를 사용하여 훈련되었지만, 원래의 추론은 `float16`을 사용합니다. Hub에 업로드된 체크포인트들은 `torch_dtype = 'float16'`을 사용하는데, 이는 `AutoModel` API가 체크포인트를 `torch.float32`에서 `torch.float16`으로 변환하는데 이용됩니다.
+
+ `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`를 사용하여 모델을 초기화할 때, 온라인 가중치의 `dtype`는 `torch_dtype="auto"`를 사용하지 않는 한 대부분 무관합니다. 그 이유는 모델이 먼저 다운로드되고(온라인 체크포인트의 `dtype`를 사용), 그 다음 `torch`의 `dtype`으로 변환되어(`torch.float32`가 됨), 마지막으로 config에 `torch_dtype`이 제공된 경우 가중치가 사용되기 때문입니다.
+
+`float16`으로 모델을 훈련하는 것은 권장되지 않으며 `nan`을 생성하는 것으로 알려져 있습니다. 따라서 모든 모델은 `bfloat16`으로 훈련되어야 합니다.
+
+
+
+팁:
+
+- 라마3 모델을 위한 가중치는 [이 폼](https://ai.meta.com/resources/models-and-libraries/llama-downloads/)을 채우면서 얻어져야 합니다.
+- 아키텍처는 라마2와 정확히 같습니다.
+- 토크나이저는 [tiktoken](https://github.com/openai/tiktoken) (sentencepiece 구현에 기반한 라마2 와는 다르게)에 기반한 BPE 모델입니다. tiktoken 기반 토크나이저가 sebtencepiece 기반 방식과 다른점은 입력 토큰이 vocab에 이미 존재할 때 BPE 병합 룰을 무시하고 싱글 토큰으로 토크나이징한다는 점에서 가장 큰 차이를 보입니다. 자세히 말하면 `"hugging"`이 vocab에 존재하고 기존에 병합이 존재하지 않으면, `["hug","ging"]` 처럼 두 토큰으로 더 작은 단위의 단어를 가지는 것이 아니라, 하나의 토큰만을 자동으로 리턴하는 것을 의미합니다.
+- 기본 모델은 패딩 토큰이 없다는 것을 의미하는 `pad_id = -1`을 사용합니다. 같은 로직을 사용할 수 없으니 `tokenizer.add_special_tokens({"pad_token":""})`를 사용하여 토큰을 추가하고 임베딩 크기도 확실히 조정해야 합니다. `model.config.pad_token_id`도 설정이 필요합니다. 모델의 `embed_tokens` 레이어는 `self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.config.padding_idx)`로 초기화되며, 패딩 토큰을 인코딩하는 것이 0(zero)를 출력하게 할 것인지 그래서 초기화가 추천될때 이를 통화시킬 것인지를 정하게 합니다.
+- 원본 체크포인트는 이 [변환 스크립트](https://github.com/huggingface/transformers/blob/main/src/transformers/models/llama/convert_llama_weights_to_hf.py)를 이용해서 변환 가능합니다. 스크립트는 다음 명령어로 호출할 수 있습니다:
+
+ ```bash
+ python src/transformers/models/llama/convert_llama_weights_to_hf.py \
+ --input_dir /path/to/downloaded/llama/weights --model_size 7B --output_dir /output/path --llama_version 3
+ ```
+
+- 변환 후, 모델과 토크나이저는 다음을 통해 로드된다.
+
+ ```python
+ from transformers import AutoModelForCausalLM, AutoTokenizer
+
+ tokenizer = AutoTokenizer.from_pretrained("/output/path")
+ model = AutoModelForCausalLM.from_pretrained("/output/path")
+ ```
+
+ 이 스크립트를 실행시키려면 모델 전체를 float16 정밀도로 호스팅할 수 있는 충분한 메인메모리가 필요하다는 점을 유의하세요. 가장 큰 버전이 여러 체크포인트로 나뉘어 있더라도, 각 체크포인트가 모델의 가중치 일부를 포함하고 있기 때문에 이를 모두 RAM에 로드해야 합니다. 75B 모델을 예로 들면 대략 145GB의 RAM이 필요합니다.
+
+- `attn_implementation="flash_attention_2"`를 통해서 플래시 어텐션2를 사용할 때, `from_pretrained` 클래스 메서드에 `torch_dtype`를 전달하지 말고 자동 혼합 정밀도(Automatic Mixed-Precision) 학습을 사용하세요. `Trainer`를 사용할 때는 단순히 `fp16` 또는 `bf16`을 `True`로 설정하면 됩니다. 그렇지 않으면 반드시 `torch.autocast`를 사용해야 합니다. 플래시 어텐션은 `fp16`과 `bf16` 데이터 유형만 지원하기 때문입니다.
+
+## 자료[[resources]]
+
+[라마2](./llama2) 문서 페이지에서는 이미 수 많은 멋지고 유익한 자료들을 제공하고 있습니다. 이곳에 라마3에 대한 새로운 자료를 더해주실 컨트리뷰터들을 초대합니다! 🤗
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/mamba.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/mamba.md
new file mode 100644
index 0000000000000000000000000000000000000000..404b9b06b41353949a8db18867d4fce4a8fa452e
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/mamba.md
@@ -0,0 +1,105 @@
+
+
+# 맘바[[mamba]]
+
+## 개요[[overview]]
+
+맘바(Mamba) 모델은 Albert Gu, Tri Dao가 제안한 [맘바: 선택적 상태 공간을 이용한 선형 시간 시퀀스 모델링](https://arxiv.org/abs/2312.00752)라는 논문에서 소개 되었습니다.
+
+이 모델은 `state-space-models`을 기반으로 한 새로운 패러다임 아키텍처입니다. 직관적인 이해를 얻고 싶다면 [이곳](https://srush.github.io/annotated-s4/)을 참고 하세요.
+
+해당 논문의 초록입니다:
+
+*현재 딥러닝에서 흥미로운 응용 프로그램을 구동하는 대부분의 기초 모델들은 거의 보편적으로 트랜스포머 아키텍처와 그 핵심 어텐션 모듈을 기반으로 합니다. 선형 어텐션, 게이트된 컨볼루션과 순환 모델, 구조화된 상태 공간 모델(SSM) 등 많은 준이차시간(subquadratic-time) 아키텍처가 긴 시퀀스에 대한 트랜스포머의 계산 비효율성을 해결하기 위해 개발되었지만, 언어와 같은 중요한 양식에서는 어텐션만큼 성능을 내지 못했습니다. 우리는 이러한 모델의 주요 약점이 내용 기반 추론을 수행하지 못한다는 점임을 알고 몇 가지를 개선했습니다. 첫째, SSM 매개변수를 입력의 함수로 만드는 것만으로도 이산 모달리티(discrete modalities)의 약점을 해결할 수 있어, 현재 토큰에 따라 시퀀스 길이 차원을 따라 정보를 선택적으로 전파하거나 잊을 수 있게 합니다. 둘째, 이러한 변경으로 효율적인 컨볼루션을 사용할 수 없게 되었지만, 우리는 순환 모드에서 하드웨어를 인식하는 병렬 알고리즘을 설계했습니다. 우리는 이러한 선택적 SSM을 어텐션이나 MLP 블록도 없는 단순화된 종단간 신경망 아키텍처인 맘바에 통합시켰습니다. 맘바는 빠른 추론(트랜스포머보다 5배 높은 처리량)과 시퀀스 길이에 대한 선형 확장성을 누리며, 백만 길이 시퀀스까지 실제 데이터에서 성능이 향상됩니다. 일반적인 시퀀스 모델 백본으로서 맘바는 언어, 오디오, 유전체학과 같은 여러 양식에서 최첨단 성능을 달성합니다. 언어 모델링에서 우리의 맘바-3B 모델은 같은 크기의 트랜스포머를 능가하고 두 배 크기의 트랜스포머와 맞먹는 성능을 보이며, 사전 훈련과 다운스트림 평가 모두에서 성능을 나타납니다.*
+
+팁:
+
+- 맘바는 고전적인 트랜스포머와 견줄 만한 새로운 `상태 공간 모델` 아키텍처입니다. 이는 구조화된 상태 공간 모델의 발전 선상에 있으며, [플래시어텐션](https://github.com/Dao-AILab/flash-attention)의 정신을 따르는 효율적인 하드웨어 인식 설계와 구현을 특징으로 합니다.
+- 맘바는 `어텐션` 레이어와 동등한 `믹서(mixer)` 레이어를 쌓습니다. `맘바`의 핵심 로직은 `MambaMixer` 클래스에 있습니다.
+- 두 가지 구현이 공존합니다: 하나는 최적화되어 빠른 cuda커널을 사용하고, 다른 하나는 단순하지만 모든 장치에서 실행할 수 있습니다!
+- 현재 구현은 원본 cuda커널을 활용합니다: 맘바를 위한 플래시 어텐션의 역할을 하는 것은 [`mamba-ssm`](https://github.com/state-spaces/mamba)와 [`causal_conv1d`](https://github.com/Dao-AILab/causal-conv1d) 저장소에 호스팅되어 있습니다. 하드웨어가 지원한다면 반드시 설치하세요!
+- cuda 커널을 최적화하는 방향 보다는, 단순하지만 모든 장치에서 실행가능하도록하는 방향인 '단순구현'의 성능을 빠르게 향상시키는 기여를 더 환영하고 있습니다. 🤗
+
+이 모델은 [ArthurZ](https://huggingface.co/ArthurZ)에 의해 기여되었습니다.
+원본 코드는 [이곳](https://github.com/state-spaces/mamba)에서 확인할 수 있습니다.
+
+# 사용
+
+### 간단한 생성 예제
+
+```python
+from transformers import MambaConfig, MambaForCausalLM, AutoTokenizer
+import torch
+
+tokenizer = AutoTokenizer.from_pretrained("state-spaces/mamba-130m-hf")
+model = MambaForCausalLM.from_pretrained("state-spaces/mamba-130m-hf")
+input_ids = tokenizer("Hey how are you doing?", return_tensors= "pt")["input_ids"]
+
+out = model.generate(input_ids, max_new_tokens=10)
+print(tokenizer.batch_decode(out))
+```
+
+### Peft 파인튜닝
+느린 버전은 학습에서 아주 안정적이진 않습니다. 빠른 버전은 `float32`가 필요합니다!
+
+```python
+from datasets import load_dataset
+from trl import SFTTrainer
+from peft import LoraConfig
+from transformers import AutoTokenizer, AutoModelForCausalLM, TrainingArguments
+model_id = "state-spaces/mamba-130m-hf"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id)
+dataset = load_dataset("Abirate/english_quotes", split="train")
+training_args = TrainingArguments(
+ output_dir="./results",
+ num_train_epochs=3,
+ per_device_train_batch_size=4,
+ logging_dir='./logs',
+ logging_steps=10,
+ learning_rate=2e-3
+)
+lora_config = LoraConfig(
+ r=8,
+ target_modules=["x_proj", "embeddings", "in_proj", "out_proj"],
+ task_type="CAUSAL_LM",
+ bias="none"
+)
+trainer = SFTTrainer(
+ model=model,
+ tokenizer=tokenizer,
+ args=training_args,
+ peft_config=lora_config,
+ train_dataset=dataset,
+ dataset_text_field="quote",
+)
+trainer.train()
+```
+
+## MambaConfig
+
+[[autodoc]] MambaConfig
+
+## MambaModel
+
+[[autodoc]] MambaModel
+ - forward
+
+## MambaLMHeadModel
+
+[[autodoc]] MambaForCausalLM
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/mamba2.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/mamba2.md
new file mode 100644
index 0000000000000000000000000000000000000000..b023914bc1276ab99a3aafb693f97b068d055e82
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/mamba2.md
@@ -0,0 +1,111 @@
+
+
+# 맘바2[[mamba-2]]
+
+## 개요[[overview]]
+
+맘바2 모델은 Tri Dao, Albert Gu가 제안한 [트랜스포머는 SSM이다: 구조화된 상태 공간 이중성을 통한 일반화된 모델과 효율적인 알고리즘](https://arxiv.org/abs/2405.21060)라는 논문에서 소개되었습니다. 맘바2는 맘바1과 유사한 상태 공간 모델로, 단순화된 아키텍처에서 더 나은 성능을 보입니다.
+
+해당 논문의 초록입니다:
+
+*트랜스포머는 언어 모델링에서 딥러닝 성공의 주요 아키텍처였지만, 맘바와 같은 상태 공간 모델(SSM)이 최근 소규모 혹은 중간 규모에서 트랜스포머와 대등하거나 더 나은 성능을 보이는 것으로 나타났습니다. 우리는 이러한 모델 계열들이 실제로 매우 밀접하게 연관되어 있음을 파악했습니다. 그리고 구조화된 준분리(semiseparable) 행렬 중 연구가 잘 이루어진 클래스의 다양한 분해를 통해 연결된 SSM과 어텐션 변형 사이의 풍부한 이론적 연결 프레임워크를 개발했습니다. 상태 공간 이중성(SSD) 프레임워크를 통해 맘바1의 선택적 SSM을 개선한 새로운 아키텍처를 설계할 수 있었고, 트랜스포머와 경쟁력을 유지하면서도 속도는 2~8배 더 빠른 성능을 냅니다.*
+
+팁:
+
+이 버전은 맘바2 구현을 지원해야 하며, 특히 Mistral AI의 [Mamba-2 codestral](https://huggingface.co/mistralai/Mamba-Codestral-7B-v0.1)을 지원합니다. 특히, mamba 2 codestral은 8개의 `groups`로 출시되었는데, 이는 어텐션 기반 모델의 KV 헤드 수와 유사하다고 판단 가능합니다.
+
+이 모델은 `torch_forward`와 `cuda_kernels_forward`라는 두 가지 다른 전방 패스를 가집니다. `cuda_kernels_forward`는 환경에서 cuda 커널을 찾으면 이를 사용하며, prefill에서는 더 느립니다. 즉, 높은 CPU 오버헤드로 인해 "웜업 실행"이 필요하기 때문입니다. 관련 내용은 [이곳](https://github.com/state-spaces/mamba/issues/389#issuecomment-2171755306)과 [이곳](https://github.com/state-spaces/mamba/issues/355#issuecomment-2147597457)을 참고하세요.
+
+컴파일 없이는 `torch_forward` 구현이 3~4배 빠릅니다. 또한, 이 모델에는 위치 임베딩이 없지만 `attention_mask`와 배치 생성의 경우 두 곳에서 은닉 상태(hidden state)를 마스킹하는 특정 로직이 있습니다. 관련 내용은 [이곳](https://github.com/state-spaces/mamba/issues/66#issuecomment-1863563829)을 참고하세요.
+
+이로인해 맘바2 커널의 재구현과 함께 배치 생성 및 캐시된 생성에서 약간의 차이가 예상됩니다. 또한 cuda 커널 또는 torch forward가 제공하는 결과가 약간 다를 것으로 예상됩니다. SSM 알고리즘은 텐서 수축에 크게 의존하는데, 이는 matmul과 동등하지만 연산 순서가 약간 다르며, 이로 인해 더 작은 정밀도에서 차이가 더 커집니다.
+
+또 다른 참고사항으로, 패딩 토큰에 해당하는 은닉 상태(hidden state)의 종료는 두 곳에서 이루어지며 주로 왼쪽 패딩으로 테스트되었습니다. 오른쪽 패딩은 노이즈를 전파하므로 만족스러운 결과를 보장하지 않습니다. `tokenizer.padding_side = "left"`를 사용하면 올바른 패딩 방향을 사용할 수 있습니다.
+
+이 모델은 [Molbap](https://huggingface.co/Molbap)이 기여했으며, [Anton Vlasjuk](https://github.com/vasqu)의 큰 도움을 받았습니다.
+원본 코드는 [이곳](https://github.com/state-spaces/mamba)에서 확인할 수 있습니다.
+
+
+# 사용
+
+### 간단한 생성 예:
+```python
+from transformers import Mamba2Config, Mamba2ForCausalLM, AutoTokenizer
+import torch
+model_id = 'mistralai/Mamba-Codestral-7B-v0.1'
+tokenizer = AutoTokenizer.from_pretrained(model_id, revision='refs/pr/9', from_slow=True, legacy=False)
+model = Mamba2ForCausalLM.from_pretrained(model_id, revision='refs/pr/9')
+input_ids = tokenizer("Hey how are you doing?", return_tensors= "pt")["input_ids"]
+
+out = model.generate(input_ids, max_new_tokens=10)
+print(tokenizer.batch_decode(out))
+```
+
+이곳은 미세조정을 위한 초안 스크립트입니다:
+```python
+from trl import SFTTrainer
+from peft import LoraConfig
+from transformers import AutoTokenizer, Mamba2ForCausalLM, TrainingArguments
+model_id = 'mistralai/Mamba-Codestral-7B-v0.1'
+tokenizer = AutoTokenizer.from_pretrained(model_id, revision='refs/pr/9', from_slow=True, legacy=False)
+tokenizer.pad_token = tokenizer.eos_token
+tokenizer.padding_side = "left" #왼쪽 패딩으로 설정
+
+model = Mamba2ForCausalLM.from_pretrained(model_id, revision='refs/pr/9')
+dataset = load_dataset("Abirate/english_quotes", split="train")
+# CUDA 커널없이는, 배치크기 2가 80GB 장치를 하나 차지합니다.
+# 하지만 정확도는 감소합니다.
+# 실험과 시도를 환영합니다!
+training_args = TrainingArguments(
+ output_dir="./results",
+ num_train_epochs=3,
+ per_device_train_batch_size=2,
+ logging_dir='./logs',
+ logging_steps=10,
+ learning_rate=2e-3
+)
+lora_config = LoraConfig(
+ r=8,
+ target_modules=["embeddings", "in_proj", "out_proj"],
+ task_type="CAUSAL_LM",
+ bias="none"
+)
+trainer = SFTTrainer(
+ model=model,
+ tokenizer=tokenizer,
+ args=training_args,
+ peft_config=lora_config,
+ train_dataset=dataset,
+ dataset_text_field="quote",
+)
+trainer.train()
+```
+
+
+## Mamba2Config
+
+[[autodoc]] Mamba2Config
+
+## Mamba2Model
+
+[[autodoc]] Mamba2Model
+ - forward
+
+## Mamba2LMHeadModel
+
+[[autodoc]] Mamba2ForCausalLM
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/marian.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/marian.md
new file mode 100644
index 0000000000000000000000000000000000000000..79a9641401d01e400c42de70d65f2157fefc97fa
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/marian.md
@@ -0,0 +1,217 @@
+
+
+# MarianMT[[MarianMT]]
+
+
+
+## 개요[[Overview]]
+
+BART와 동일한 모델을 사용하는 번역 모델 프레임워크입니다. 번역 결과는 각 모델 카드의 테스트 세트와 유사하지만, 정확히 일치하지는 않을 수 있습니다. 이 모델은 [sshleifer](https://huggingface.co/sshleifer)가 제공했습니다.
+
+
+## 구현 노트[[Implementation Notes]]
+
+- 각 모델은 약 298 MB를 차지하며, 1,000개 이상의 모델이 제공됩니다.
+- 지원되는 언어 쌍 목록은 [여기](https://huggingface.co/Helsinki-NLP)에서 확인할 수 있습니다.
+- 모델들은 [Jörg Tiedemann](https://researchportal.helsinki.fi/en/persons/j%C3%B6rg-tiedemann)에 의해 [Marian](https://marian-nmt.github.io/) C++ 라이브러리를 이용하여 학습되었습니다. 이 라이브러리는 빠른 학습과 번역을 지원합니다.
+- 모든 모델은 6개 레이어로 이루어진 Transformer 기반의 인코더-디코더 구조입니다. 각 모델의 성능은 모델 카드에 기입되어 있습니다.
+- BPE 전처리가 필요한 80개의 OPUS 모델은 지원되지 않습니다.
+- 모델링 코드는 [`BartForConditionalGeneration`]을 기반으로 하며, 일부 수정사항이 반영되어 있습니다:
+
+ - 정적 (사인 함수 기반) 위치 임베딩 사용 (`MarianConfig.static_position_embeddings=True`)
+ - 임베딩 레이어 정규화 생략 (`MarianConfig.normalize_embedding=False`)
+ - 모델은 생성 시 프리픽스로 `pad_token_id` (해당 토큰 임베딩 값은 0)를 사용하여 시작합니다 (Bart는
+ `
+
+
+## MarianModel
+
+[[autodoc]] MarianModel
+ - forward
+
+## MarianMTModel
+
+[[autodoc]] MarianMTModel
+ - forward
+
+## MarianForCausalLM
+
+[[autodoc]] MarianForCausalLM
+ - forward
+
+
+
+
+## TFMarianModel
+
+[[autodoc]] TFMarianModel
+ - call
+
+## TFMarianMTModel
+
+[[autodoc]] TFMarianMTModel
+ - call
+
+
+
+
+## FlaxMarianModel
+
+[[autodoc]] FlaxMarianModel
+ - __call__
+
+## FlaxMarianMTModel
+
+[[autodoc]] FlaxMarianMTModel
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/mistral.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/mistral.md
new file mode 100644
index 0000000000000000000000000000000000000000..4c9f2d7a77d4a2fee499e4db14e88f4c122c10e5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/mistral.md
@@ -0,0 +1,233 @@
+
+
+# Mistral[[mistral]]
+
+## 개요[[overview]]
+
+미스트랄은 Albert Jiang, Alexandre Sablayrolles, Arthur Mensch, Chris Bamford, Devendra Singh Chaplot, Diego de las Casas, Florian Bressand, Gianna Lengyel, Guillaume Lample, Lélio Renard Lavaud, Lucile Saulnier, Marie-Anne Lachaux, Pierre Stock, Teven Le Scao, Thibaut Lavril, Thomas Wang, Timothée Lacroix, William El Sayed가 작성한 [이 블로그 포스트](https://mistral.ai/news/announcing-mistral-7b/)에서 소개되었습니다.
+
+블로그 포스트의 서두는 다음과 같습니다:
+
+*미스트랄 AI팀은 현존하는 언어 모델 중 크기 대비 가장 강력한 미스트랄7B를 출시하게 되어 자랑스럽습니다.*
+
+미스트랄-7B는 [mistral.ai](https://mistral.ai/)에서 출시한 첫 번째 대규모 언어 모델(LLM)입니다.
+
+### 아키텍처 세부사항[[architectural-details]]
+
+미스트랄-7B는 다음과 같은 구조적 특징을 가진 디코더 전용 트랜스포머입니다:
+
+- 슬라이딩 윈도우 어텐션: 8k 컨텍스트 길이와 고정 캐시 크기로 훈련되었으며, 이론상 128K 토큰의 어텐션 범위를 가집니다.
+- GQA(Grouped Query Attention): 더 빠른 추론이 가능하고 더 작은 크기의 캐시를 사용합니다.
+- 바이트 폴백(Byte-fallback) BPE 토크나이저: 문자들이 절대 어휘 목록 외의 토큰으로 매핑되지 않도록 보장합니다.
+
+더 자세한 내용은 [출시 블로그 포스트](https://mistral.ai/news/announcing-mistral-7b/)를 참조하세요.
+
+### 라이선스[[license]]
+
+`미스트랄-7B`는 아파치 2.0 라이선스로 출시되었습니다.
+
+## 사용 팁[[usage-tips]]
+
+미스트랄 AI팀은 다음 3가지 체크포인트를 공개했습니다:
+
+- 기본 모델인 [미스트랄-7B-v0.1](https://huggingface.co/mistralai/Mistral-7B-v0.1)은 인터넷 규모의 데이터에서 다음 토큰을 예측하도록 사전 훈련되었습니다.
+- 지시 조정 모델인 [미스트랄-7B-Instruct-v0.1](https://huggingface.co/mistralai/Mistral-7B-Instruct-v0.1)은 지도 미세 조정(SFT)과 직접 선호도 최적화(DPO)를 사용한 채팅에 최적화된 기본 모델입니다.
+- 개선된 지시 조정 모델인 [미스트랄-7B-Instruct-v0.2](https://huggingface.co/mistralai/Mistral-7B-Instruct-v0.2)는 v1을 개선한 버전입니다.
+
+기본 모델은 다음과 같이 사용할 수 있습니다:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-v0.1", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to("cuda")
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"My favourite condiment is to ..."
+```
+
+지시 조정 모델은 다음과 같이 사용할 수 있습니다:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-Instruct-v0.2", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-Instruct-v0.2")
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to("cuda")
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"Mayonnaise can be made as follows: (...)"
+```
+
+지시 조정 모델은 입력이 올바른 형식으로 준비되도록 [채팅 템플릿](../chat_templating)을 적용해야 합니다.
+
+## 플래시 어텐션을 이용한 미스트랄 속도향상[[speeding-up-mistral-by-using-flash-attention]]
+
+위의 코드 스니펫들은 어떤 최적화 기법도 사용하지 않은 추론 과정을 보여줍니다. 하지만 모델 내부에서 사용되는 어텐션 메커니즘의 더 빠른 구현인 [플래시 어텐션2](../perf_train_gpu_one.md#flash-attention-2)을 활용하면 모델의 속도를 크게 높일 수 있습니다.
+
+먼저, 슬라이딩 윈도우 어텐션 기능을 포함하는 플래시 어텐션2의 최신 버전을 설치해야 합니다.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+하드웨어와 플래시 어텐션2의 호환여부를 확인하세요. 이에 대한 자세한 내용은 [플래시 어텐션 저장소](https://github.com/Dao-AILab/flash-attention)의 공식 문서에서 확인할 수 있습니다. 또한 모델을 반정밀도(예: `torch.float16`)로 불러와야합니다.
+
+플래시 어텐션2를 사용하여 모델을 불러오고 실행하려면 아래 코드 스니펫을 참조하세요:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-v0.1", torch_dtype=torch.float16, attn_implementation="flash_attention_2", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to("cuda")
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"My favourite condiment is to (...)"
+```
+
+### 기대하는 속도 향상[[expected-speedups]]
+
+다음은 `mistralai/Mistral-7B-v0.1` 체크포인트를 사용한 트랜스포머의 기본 구현과 플래시 어텐션2 버전 모델 사이의 순수 추론 시간을 비교한 예상 속도 향상 다이어그램입니다.
+
+
+
+
+
+
+## OpenAIGPTModel [[transformers.OpenAIGPTModel]]
+
+[[autodoc]] OpenAIGPTModel
+ - forward
+
+## OpenAIGPTLMHeadModel [[transformers.OpenAIGPTLMHeadModel]]
+
+[[autodoc]] OpenAIGPTLMHeadModel
+ - forward
+
+## OpenAIGPTDoubleHeadsModel [[transformers.OpenAIGPTDoubleHeadsModel]]
+
+[[autodoc]] OpenAIGPTDoubleHeadsModel
+ - forward
+
+## OpenAIGPTForSequenceClassification [[transformers.OpenAIGPTForSequenceClassification]]
+
+[[autodoc]] OpenAIGPTForSequenceClassification
+ - forward
+
+
+
+
+## TFOpenAIGPTModel [[transformers.TFOpenAIGPTModel]]
+
+[[autodoc]] TFOpenAIGPTModel
+ - call
+
+## TFOpenAIGPTLMHeadModel [[transformers.TFOpenAIGPTLMHeadModel]]
+
+[[autodoc]] TFOpenAIGPTLMHeadModel
+ - call
+
+## TFOpenAIGPTDoubleHeadsModel [[transformers.TFOpenAIGPTDoubleHeadsModel]]
+
+[[autodoc]] TFOpenAIGPTDoubleHeadsModel
+ - call
+
+## TFOpenAIGPTForSequenceClassification [[transformers.TFOpenAIGPTForSequenceClassification]]
+
+[[autodoc]] TFOpenAIGPTForSequenceClassification
+ - call
+
+
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/paligemma.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/paligemma.md
new file mode 100644
index 0000000000000000000000000000000000000000..9f5b48086855094ed1d0ad9e746c486760c60ef5
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/paligemma.md
@@ -0,0 +1,80 @@
+
+
+# PaliGemma[[paligemma]]
+
+## 개요[[overview]]
+
+PaliGemma 모델은 구글이 제안한 [PaliGemma – Google의 최첨단 오픈 비전 언어 모델](https://huggingface.co/blog/paligemma)에서 소개 되었습니다. PaliGemma는 [SigLIP](siglip) 비전 인코더와 [Gemma](gemma) 언어 인코더로 구성된 3B 규모의 비전-언어 모델로, 두 인코더가 멀티모달 선형 프로젝션으로 연결되어 있습니다. 이 모델은 이미지를 고정된 수의 VIT토큰으로 분할하고 이를 선택적 프롬프트 앞에 추가 하며, 모든 이미지 토큰과 입력 텍스트 토큰에 대해 전체 블록 어텐션을 사용하는 특징을 가지고 있습니다.
+
+PaliGemma는 224x224, 448x448, 896x896의 3가지 해상도로 제공되며, 3개의 기본 모델과 55개의 다양한 작업에 대해 미세 조정된 버전, 그리고 2개의 혼합 모델이 있습니다.
+
+ PaliGemma 아키텍처 블로그 포스트.
+
+이 모델은 [Molbap](https://huggingface.co/Molbap)에 의해 기여 되었습니다.
+
+## 사용 팁[[usage-tips]]
+
+PaliGemma의 추론은 다음처럼 수행됩니다:
+
+```python
+from transformers import AutoProcessor, PaliGemmaForConditionalGeneration
+
+model_id = "google/paligemma-3b-mix-224"
+model = PaliGemmaForConditionalGeneration.from_pretrained(model_id)
+processor = AutoProcessor.from_pretrained(model_id)
+
+prompt = "What is on the flower?"
+image_file = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg?download=true"
+raw_image = Image.open(requests.get(image_file, stream=True).raw)
+inputs = processor(raw_image, prompt, return_tensors="pt")
+output = model.generate(**inputs, max_new_tokens=20)
+
+print(processor.decode(output[0], skip_special_tokens=True)[len(prompt):])
+```
+
+- PaliGemma는 대화용으로 설계되지 않았으며, 특정 사용 사례에 대해 미세 조정할 때 가장 잘 작동합니다. PaliGemma를 미세 조정할 수 있는 몇 가지 하위 작업에는 이미지 캡셔닝, 시각적 질문 답변(VQA), 오브젝트 디텍션, 참조 표현 분할 및 문서 이해가 포함됩니다.
+- 모델에 필요한 이미지, 텍스트 및 선택적 레이블을 준비하는데 `PaliGemmaProcessor`를 사용할 수 있습니다. PaliGemma 모델을 미세 조정할 때는, 프로세서에 `suffix`인자를 전달하여 다음 처럼 모델의 `labels`를 생성할 수 있습니다:
+
+```python
+prompt = "What is on the flower?"
+answer = "a bee"
+inputs = processor(images=raw_image, text=prompt, suffix=answer, return_tensors="pt")
+```
+
+## 자료[[resources]]
+
+PaliGemma를 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다.여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+- PaliGemma의 모든 기능을 소개하는 블로그 포스트는 [이곳](https://huggingface.co/blog/paligemma)에서 찾을 수 있습니다. 🌎
+- Trainer API를 사용하여 VQA(Visual Question Answering)를 위해 PaliGemma를 미세 조정하는 방법과 추론에 대한 데모 노트북은 [이곳](https://github.com/huggingface/notebooks/tree/main/examples/paligemma)에서 찾을 수 있습니다. 🌎
+- 사용자 정의 데이터셋(영수증 이미지 -> JSON)에 대해 PaliGemma를 미세 조정하는 방법과 추론에 대한 데모 노트북은 [이곳](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/PaliGemma)에서 찾을 수 있습니다. 🌎
+
+## PaliGemmaConfig[[transformers.PaliGemmaConfig]]
+
+[[autodoc]] PaliGemmaConfig
+
+## PaliGemmaProcessor[[transformers.PaliGemmaProcessor]]
+
+[[autodoc]] PaliGemmaProcessor
+
+## PaliGemmaForConditionalGeneration[[transformers.PaliGemmaForConditionalGeneration]]
+
+[[autodoc]] PaliGemmaForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/patchtsmixer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/patchtsmixer.md
new file mode 100644
index 0000000000000000000000000000000000000000..e1463eb85de3e5aca2623fe038da4b249f9c629c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/patchtsmixer.md
@@ -0,0 +1,95 @@
+
+
+# PatchTSMixer[[patchtsmixer]]
+
+## 개요[[overview]]
+
+PatchTSMixer 모델은 Vijay Ekambaram, Arindam Jati, Nam Nguyen, Phanwadee Sinthong, Jayant Kalagnanam이 제안한 [TSMixer: 다변량 시계열 예측을 위한 경량 MLP-Mixer 모델](https://arxiv.org/pdf/2306.09364.pdf)이라는 논문에서 소개되었습니다.
+
+
+PatchTSMixer는 MLP-Mixer 아키텍처를 기반으로 한 경량 시계열 모델링 접근법입니다. 허깅페이스 구현에서는 PatchTSMixer의 기능을 제공하여 패치, 채널, 숨겨진 특성 간의 경량 혼합을 쉽게 수행하여 효과적인 다변량 시계열 모델링을 가능하게 합니다. 또한 간단한 게이트 어텐션부터 사용자 정의된 더 복잡한 셀프 어텐션 블록까지 다양한 어텐션 메커니즘을 지원합니다. 이 모델은 사전 훈련될 수 있으며 이후 예측, 분류, 회귀와 같은 다양한 다운스트림 작업에 사용될 수 있습니다.
+
+
+해당 논문의 초록입니다:
+
+*TSMixer는 패치 처리된 시계열의 다변량 예측 및 표현 학습을 위해 설계된 다층 퍼셉트론(MLP) 모듈로만 구성된 경량 신경망 아키텍처입니다. 우리의 모델은 컴퓨터 비전 분야에서 MLP-Mixer 모델의 성공에서 영감을 받았습니다. 우리는 Vision MLP-Mixer를 시계열에 적용하는 데 따르는 과제를 보여주고, 정확도를 향상시키기 위해 경험적으로 검증된 구성 요소들을 도입합니다. 여기에는 계층 구조 및 채널 상관관계와 같은 시계열 특성을 명시적으로 모델링하기 위해 MLP-Mixer 백본에 온라인 조정 헤드를 부착하는 새로운 설계 패러다임이 포함됩니다. 또한 기존 패치 채널 혼합 방법의 일반적인 문제인 노이즈가 있는 채널 상호작용을 효과적으로 처리하고 다양한 데이터셋에 걸쳐 일반화하기 위한 하이브리드 채널 모델링 접근법을 제안합니다. 추가로, 중요한 특성을 우선시하기 위해 백본에 간단한 게이트 주의 메커니즘을 도입합니다. 이러한 경량 구성 요소들을 통합함으로써, 우리는 단순한 MLP 구조의 학습 능력을 크게 향상시켜 최소한의 컴퓨팅 사용으로 복잡한 트랜스포머 모델들을 능가하는 성능을 달성합니다. 더욱이, TSMixer의 모듈식 설계는 감독 학습과 마스크 자기 감독 학습 방법 모두와 호환되어 시계열 기초 모델의 유망한 구성 요소가 됩니다. TSMixer는 예측 작업에서 최첨단 MLP 및 트랜스포머 모델들을 상당한 차이(8-60%)로 능가합니다. 또한 최신의 강력한 Patch-Transformer 모델 벤치마크들을 메모리와 실행 시간을 크게 줄이면서(2-3배) 성능 면에서도 앞섭니다(1-2%).*
+
+이 모델은 [ajati](https://huggingface.co/ajati), [vijaye12](https://huggingface.co/vijaye12),
+[gsinthong](https://huggingface.co/gsinthong), [namctin](https://huggingface.co/namctin),
+[wmgifford](https://huggingface.co/wmgifford), [kashif](https://huggingface.co/kashif)가 기여했습니다.
+
+## 사용 예[[usage-example]]
+
+아래의 코드 스니펫은 PatchTSMixer 모델을 무작위로 초기화하는 방법을 보여줍니다.
+PatchTSMixer 모델은 [Trainer API](../trainer.md)와 호환됩니다.
+
+```python
+
+from transformers import PatchTSMixerConfig, PatchTSMixerForPrediction
+from transformers import Trainer, TrainingArguments,
+
+
+config = PatchTSMixerConfig(context_length = 512, prediction_length = 96)
+model = PatchTSMixerForPrediction(config)
+trainer = Trainer(model=model, args=training_args,
+ train_dataset=train_dataset,
+ eval_dataset=valid_dataset)
+trainer.train()
+results = trainer.evaluate(test_dataset)
+```
+
+## 사용 팁[[usage-tips]]
+
+이 모델은 시계열 분류와 시계열 회귀에도 사용될 수 있습니다. 각각[`PatchTSMixerForTimeSeriesClassification`]와 [`PatchTSMixerForRegression`] 클래스를 참조하세요.
+
+## 자료[[resources]]
+
+- PatchTSMixer를 자세히 설명하는 블로그 포스트는 여기에서 찾을 수 있습니다 [이곳](https://huggingface.co/blog/patchtsmixer). 이 블로그는 Google Colab에서도 열어볼 수 있습니다.
+
+## PatchTSMixerConfig[[transformers.PatchTSMixerConfig]]
+
+[[autodoc]] PatchTSMixerConfig
+
+
+## PatchTSMixerModel[[transformers.PatchTSMixerModel]]
+
+[[autodoc]] PatchTSMixerModel
+ - forward
+
+
+## PatchTSMixerForPrediction[[transformers.PatchTSMixerForPrediction]]
+
+[[autodoc]] PatchTSMixerForPrediction
+ - forward
+
+
+## PatchTSMixerForTimeSeriesClassification[[transformers.PatchTSMixerForTimeSeriesClassification]]
+
+[[autodoc]] PatchTSMixerForTimeSeriesClassification
+ - forward
+
+
+## PatchTSMixerForPretraining[[transformers.PatchTSMixerForPretraining]]
+
+[[autodoc]] PatchTSMixerForPretraining
+ - forward
+
+
+## PatchTSMixerForRegression[[transformers.PatchTSMixerForRegression]]
+
+[[autodoc]] PatchTSMixerForRegression
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/patchtst.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/patchtst.md
new file mode 100644
index 0000000000000000000000000000000000000000..fc9b0eb51e4a427b26f832a30e8d5c007e9a9bb1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/patchtst.md
@@ -0,0 +1,76 @@
+
+
+# PatchTST[[patchtst]]
+
+## 개요[[overview]]
+
+The PatchTST 모델은 Yuqi Nie, Nam H. Nguyen, Phanwadee Sinthong, Jayant Kalagnanam이 제안한 [시계열 하나가 64개의 단어만큼 가치있다: 트랜스포머를 이용한 장기예측](https://arxiv.org/abs/2211.14730)라는 논문에서 소개되었습니다.
+
+이 모델은 고수준에서 시계열을 주어진 크기의 패치로 벡터화하고, 결과로 나온 벡터 시퀀스를 트랜스포머를 통해 인코딩한 다음 적절한 헤드를 통해 예측 길이의 예측을 출력합니다. 모델은 다음 그림과 같이 도식화됩니다:
+
+
+
+해당 논문의 초록입니다:
+
+*우리는 다변량 시계열 예측과 자기 감독 표현 학습을 위한 효율적인 트랜스포머 기반 모델 설계를 제안합니다. 이는 두 가지 주요 구성 요소를 기반으로 합니다:
+
+(i) 시계열을 하위 시리즈 수준의 패치로 분할하여 트랜스포머의 입력 토큰으로 사용
+(ii) 각 채널이 모든 시리즈에 걸쳐 동일한 임베딩과 트랜스포머 가중치를 공유하는 단일 단변량 시계열을 포함하는 채널 독립성. 패칭 설계는 자연스럽게 세 가지 이점을 가집니다:
+ - 지역적 의미 정보가 임베딩에 유지됩니다;
+ - 동일한 룩백 윈도우에 대해 어텐션 맵의 계산과 메모리 사용량이 제곱으로 감소합니다
+ - 모델이 더 긴 과거를 참조할 수 있습니다.
+ 우리의 채널 독립적 패치 시계열 트랜스포머(PatchTST)는 최신 트랜스포머 기반 모델들과 비교했을 때 장기 예측 정확도를 크게 향상시킬 수 있습니다. 또한 모델을 자기지도 사전 훈련 작업에 적용하여, 대규모 데이터셋에 대한 지도 학습을 능가하는 아주 뛰어난 미세 조정 성능을 달성했습니다. 한 데이터셋에서 마스크된 사전 훈련 표현을 다른 데이터셋으로 전이하는 것도 최고 수준의 예측 정확도(SOTA)를 산출했습니다.*
+
+이 모델은 [namctin](https://huggingface.co/namctin), [gsinthong](https://huggingface.co/gsinthong), [diepi](https://huggingface.co/diepi), [vijaye12](https://huggingface.co/vijaye12), [wmgifford](https://huggingface.co/wmgifford), [kashif](https://huggingface.co/kashif)에 의해 기여 되었습니다. 원본코드는 [이곳](https://github.com/yuqinie98/PatchTST)에서 확인할 수 있습니다.
+
+## 사용 팁[[usage-tips]]
+
+이 모델은 시계열 분류와 시계열 회귀에도 사용될 수 있습니다. 각각 [`PatchTSTForClassification`]와 [`PatchTSTForRegression`] 클래스를 참조하세요.
+
+## 자료[[resources]]
+
+- PatchTST를 자세히 설명하는 블로그 포스트는 [이곳](https://huggingface.co/blog/patchtst)에서 찾을 수 있습니다.
+이 블로그는 Google Colab에서도 열어볼 수 있습니다.
+
+## PatchTSTConfig[[transformers.PatchTSTConfig]]
+
+[[autodoc]] PatchTSTConfig
+
+## PatchTSTModel[[transformers.PatchTSTModel]]
+
+[[autodoc]] PatchTSTModel
+ - forward
+
+## PatchTSTForPrediction[[transformers.PatchTSTForPrediction]]
+
+[[autodoc]] PatchTSTForPrediction
+ - forward
+
+## PatchTSTForClassification[[transformers.PatchTSTForClassification]]
+
+[[autodoc]] PatchTSTForClassification
+ - forward
+
+## PatchTSTForPretraining[[transformers.PatchTSTForPretraining]]
+
+[[autodoc]] PatchTSTForPretraining
+ - forward
+
+## PatchTSTForRegression[[transformers.PatchTSTForRegression]]
+
+[[autodoc]] PatchTSTForRegression
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/rag.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/rag.md
new file mode 100644
index 0000000000000000000000000000000000000000..0ae88cc7ac5e3e08fc85a3619fb59aaef54a86a1
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/ko/model_doc/rag.md
@@ -0,0 +1,100 @@
+
+
+# RAG(검색 증강 생성) [[rag]]
+
+
+
+## 개요 [[overview]]
+
+검색 증강 생성(Retrieval-augmented generation, "RAG") 모델은 사전 훈련된 밀집 검색(DPR)과 시퀀스-투-시퀀스 모델의 장점을 결합합니다. RAG 모델은 문서를 검색하고, 이를 시퀀스-투-시퀀스 모델에 전달한 다음, 주변화(marginalization)를 통해 출력을 생성합니다. 검색기와 시퀀스-투-시퀀스 모듈은 사전 훈련된 모델로 초기화되며, 함께 미세 조정되어 검색과 생성 모두 다운스트림 작업(모델을 특정 태스크에 적용하는 것)에 적응할 수 있게 합니다.
+
+이 모델은 Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela의 논문 [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://arxiv.org/abs/2005.11401)를 기반으로 합니다.
+
+논문의 초록은 다음과 같습니다.
+
+*대규모 사전 훈련 언어 모델들은 그들의 매개변수에 사실적 지식을 저장하고 있으며, 다운스트림 NLP 작업에 대해 미세 조정될 때 최첨단 결과를 달성합니다. 그러나 지식에 접근하고 정확하게 조작하는 능력은 여전히 제한적이며, 따라서 지식 집약적 작업에서 그들의 성능은 작업별 아키텍처에 비해 뒤떨어집니다. 또한, 그들의 결정에 대한 근거를 제공하고 세계 지식을 업데이트하는 것은 여전히 열린 연구 문제로 남아 있습니다. 명시적 비매개변수 메모리에 대한 미분 가능한 접근 메커니즘을 가진 사전 훈련 모델은 이 문제를 극복할 수 있지만, 지금까지는 추출적 다운스트림 작업에 대해서만 연구되었습니다. 우리는 언어 생성을 위해 사전 훈련된 매개변수 및 비매개변수 메모리를 결합하는 모델인 검색 증강 생성(RAG)에 대한 일반적인 목적의 미세 조정 방법을 탐구합니다. 우리는 매개변수 메모리가 사전 훈련된 시퀀스-투-시퀀스 모델이고 비매개변수 메모리가 사전 훈련된 신경 검색기로 접근되는 위키피디아의 밀집 벡터 인덱스인 RAG 모델을 소개합니다. 우리는 생성된 전체 시퀀스에 걸쳐 동일한 검색된 구절을 조건으로 하는 RAG 공식과 토큰별로 다른 구절을 사용할 수 있는 RAG 공식을 비교합니다. 우리는 광범위한 지식 집약적 NLP 작업에 대해 모델을 미세 조정하고 평가하며, 매개변수 시퀀스-투-시퀀스 모델과 작업별 검색-추출 아키텍처를 능가하여 세 가지 개방형 도메인 QA 작업에서 최첨단 성능을 달성합니다. 언어 생성 작업의 경우, RAG 모델이 최첨단 매개변수 전용 시퀀스-투-시퀀스 기준선보다 더 구체적이고, 다양하며, 사실적인 언어를 생성한다는 것을 발견했습니다.*
+
+이 모델은 [ola13](https://huggingface.co/ola13)에 의해 기여되었습니다.
+
+## 사용 팁 [[usage-tips]]
+
+검색 증강 생성(Retrieval-augmented generation, "RAG") 모델은 사전 훈련된 밀집 검색(DPR)과 시퀀스-투-시퀀스 모델의 강점을 결합합니다. RAG 모델은 문서를 검색하고, 이를 시퀀스-투-시퀀스 모델에 전달한 다음, 주변화(marginalization)를 통해 출력을 생성합니다. 검색기와 시퀀스-투-시퀀스 모듈은 사전 훈련된 모델로 초기화되며, 함께 미세 조정됩니다. 이를 통해 검색과 생성 모두 다운스트림 작업에 적응할 수 있게 됩니다.
+
+## RagConfig [[transformers.RagConfig]]
+
+[[autodoc]] RagConfig
+
+## RagTokenizer [[transformers.RagTokenizer]]
+
+[[autodoc]] RagTokenizer
+
+## Rag specific outputs [[transformers.models.rag.modeling_rag.RetrievAugLMMarginOutput]]
+
+[[autodoc]] models.rag.modeling_rag.RetrievAugLMMarginOutput
+
+[[autodoc]] models.rag.modeling_rag.RetrievAugLMOutput
+
+## RagRetriever [[transformers.RagRetriever]]
+
+[[autodoc]] RagRetriever
+
+
+
+
+## RagModel [[transformers.RagModel]]
+
+[[autodoc]] RagModel
+ - forward
+
+## RagSequenceForGeneration [[transformers.RagSequenceForGeneration]]
+
+[[autodoc]] RagSequenceForGeneration
+ - forward
+ - generate
+
+## RagTokenForGeneration [[transformers.RagTokenForGeneration]]
+
+[[autodoc]] RagTokenForGeneration
+ - forward
+ - generate
+
+
+
+
+## TFRagModel [[transformers.TFRagModel]]
+
+[[autodoc]] TFRagModel
+ - call
+
+## TFRagSequenceForGeneration [[transformers.TFRagSequenceForGeneration]]
+
+[[autodoc]] TFRagSequenceForGeneration
+ - call
+ - generate
+
+## TFRagTokenForGeneration [[transformers.TFRagTokenForGeneration]]
+
+[[autodoc]] TFRagTokenForGeneration
+ - call
+ - generate
+
+
+
 +
+
+
 +
+
+
 +
+
 +
+ Swin Transformer architecture. Taken from the original paper.
+
+This model was contributed by [novice03](https://huggingface.co/novice03). The Tensorflow version of this model was contributed by [amyeroberts](https://huggingface.co/amyeroberts). The original code can be found [here](https://github.com/microsoft/Swin-Transformer).
+
+## Usage tips
+
+- Swin pads the inputs supporting any input height and width (if divisible by `32`).
+- Swin can be used as a *backbone*. When `output_hidden_states = True`, it will output both `hidden_states` and `reshaped_hidden_states`. The `reshaped_hidden_states` have a shape of `(batch, num_channels, height, width)` rather than `(batch_size, sequence_length, num_channels)`.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Swin Transformer.
+
+
 +
+ Swin2SR architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/mv-lab/swin2sr).
+
+## Resources
+
+Demo notebooks for Swin2SR can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Swin2SR).
+
+A demo Space for image super-resolution with SwinSR can be found [here](https://huggingface.co/spaces/jjourney1125/swin2sr).
+
+## Swin2SRImageProcessor
+
+[[autodoc]] Swin2SRImageProcessor
+ - preprocess
+
+## Swin2SRConfig
+
+[[autodoc]] Swin2SRConfig
+
+## Swin2SRModel
+
+[[autodoc]] Swin2SRModel
+ - forward
+
+## Swin2SRForImageSuperResolution
+
+[[autodoc]] Swin2SRForImageSuperResolution
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/swinv2.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/swinv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..25233dca33954554c92f177fe076a779e99f0be6
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/swinv2.md
@@ -0,0 +1,62 @@
+
+
+# Swin Transformer V2
+
+## Overview
+
+The Swin Transformer V2 model was proposed in [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883) by Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo.
+
+The abstract from the paper is the following:
+
+*Large-scale NLP models have been shown to significantly improve the performance on language tasks with no signs of saturation. They also demonstrate amazing few-shot capabilities like that of human beings. This paper aims to explore large-scale models in computer vision. We tackle three major issues in training and application of large vision models, including training instability, resolution gaps between pre-training and fine-tuning, and hunger on labelled data. Three main techniques are proposed: 1) a residual-post-norm method combined with cosine attention to improve training stability; 2) A log-spaced continuous position bias method to effectively transfer models pre-trained using low-resolution images to downstream tasks with high-resolution inputs; 3) A self-supervised pre-training method, SimMIM, to reduce the needs of vast labeled images. Through these techniques, this paper successfully trained a 3 billion-parameter Swin Transformer V2 model, which is the largest dense vision model to date, and makes it capable of training with images of up to 1,536×1,536 resolution. It set new performance records on 4 representative vision tasks, including ImageNet-V2 image classification, COCO object detection, ADE20K semantic segmentation, and Kinetics-400 video action classification. Also note our training is much more efficient than that in Google's billion-level visual models, which consumes 40 times less labelled data and 40 times less training time.*
+
+This model was contributed by [nandwalritik](https://huggingface.co/nandwalritik).
+The original code can be found [here](https://github.com/microsoft/Swin-Transformer).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Swin Transformer v2.
+
+
 +
+ Table detection and table structure recognition clarified. Taken from the original paper.
+
+The authors released 2 models, one for [table detection](https://huggingface.co/microsoft/table-transformer-detection) in
+documents, one for [table structure recognition](https://huggingface.co/microsoft/table-transformer-structure-recognition)
+(the task of recognizing the individual rows, columns etc. in a table).
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be
+found [here](https://github.com/microsoft/table-transformer).
+
+## Resources
+
+
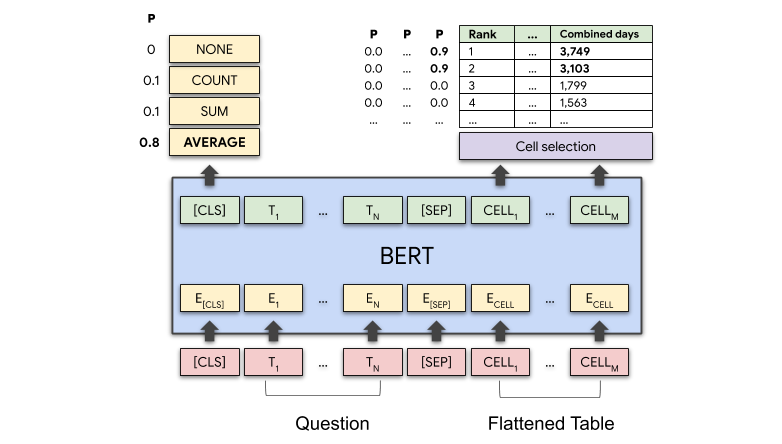 +
+ TAPAS architecture. Taken from the original blog post.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The Tensorflow version of this model was contributed by [kamalkraj](https://huggingface.co/kamalkraj). The original code can be found [here](https://github.com/google-research/tapas).
+
+## Usage tips
+
+- TAPAS is a model that uses relative position embeddings by default (restarting the position embeddings at every cell of the table). Note that this is something that was added after the publication of the original TAPAS paper. According to the authors, this usually results in a slightly better performance, and allows you to encode longer sequences without running out of embeddings. This is reflected in the `reset_position_index_per_cell` parameter of [`TapasConfig`], which is set to `True` by default. The default versions of the models available on the [hub](https://huggingface.co/models?search=tapas) all use relative position embeddings. You can still use the ones with absolute position embeddings by passing in an additional argument `revision="no_reset"` when calling the `from_pretrained()` method. Note that it's usually advised to pad the inputs on the right rather than the left.
+- TAPAS is based on BERT, so `TAPAS-base` for example corresponds to a `BERT-base` architecture. Of course, `TAPAS-large` will result in the best performance (the results reported in the paper are from `TAPAS-large`). Results of the various sized models are shown on the [original GitHub repository](https://github.com/google-research/tapas).
+- TAPAS has checkpoints fine-tuned on SQA, which are capable of answering questions related to a table in a conversational set-up. This means that you can ask follow-up questions such as "what is his age?" related to the previous question. Note that the forward pass of TAPAS is a bit different in case of a conversational set-up: in that case, you have to feed every table-question pair one by one to the model, such that the `prev_labels` token type ids can be overwritten by the predicted `labels` of the model to the previous question. See "Usage" section for more info.
+- TAPAS is similar to BERT and therefore relies on the masked language modeling (MLM) objective. It is therefore efficient at predicting masked tokens and at NLU in general, but is not optimal for text generation. Models trained with a causal language modeling (CLM) objective are better in that regard. Note that TAPAS can be used as an encoder in the EncoderDecoderModel framework, to combine it with an autoregressive text decoder such as GPT-2.
+
+## Usage: fine-tuning
+
+Here we explain how you can fine-tune [`TapasForQuestionAnswering`] on your own dataset.
+
+**STEP 1: Choose one of the 3 ways in which you can use TAPAS - or experiment**
+
+Basically, there are 3 different ways in which one can fine-tune [`TapasForQuestionAnswering`], corresponding to the different datasets on which Tapas was fine-tuned:
+
+1. SQA: if you're interested in asking follow-up questions related to a table, in a conversational set-up. For example if you first ask "what's the name of the first actor?" then you can ask a follow-up question such as "how old is he?". Here, questions do not involve any aggregation (all questions are cell selection questions).
+2. WTQ: if you're not interested in asking questions in a conversational set-up, but rather just asking questions related to a table, which might involve aggregation, such as counting a number of rows, summing up cell values or averaging cell values. You can then for example ask "what's the total number of goals Cristiano Ronaldo made in his career?". This case is also called **weak supervision**, since the model itself must learn the appropriate aggregation operator (SUM/COUNT/AVERAGE/NONE) given only the answer to the question as supervision.
+3. WikiSQL-supervised: this dataset is based on WikiSQL with the model being given the ground truth aggregation operator during training. This is also called **strong supervision**. Here, learning the appropriate aggregation operator is much easier.
+
+To summarize:
+
+| **Task** | **Example dataset** | **Description** |
+|-------------------------------------|---------------------|---------------------------------------------------------------------------------------------------------|
+| Conversational | SQA | Conversational, only cell selection questions |
+| Weak supervision for aggregation | WTQ | Questions might involve aggregation, and the model must learn this given only the answer as supervision |
+| Strong supervision for aggregation | WikiSQL-supervised | Questions might involve aggregation, and the model must learn this given the gold aggregation operator |
+
+
 +
+ TextNet backbone as part of FAST. Taken from the original paper.
+
+This model was contributed by [Raghavan](https://huggingface.co/Raghavan), [jadechoghari](https://huggingface.co/jadechoghari) and [nielsr](https://huggingface.co/nielsr).
+
+## Usage tips
+
+TextNet is mainly used as a backbone network for the architecture search of text detection. Each stage of the backbone network is comprised of a stride-2 convolution and searchable blocks.
+Specifically, we present a layer-level candidate set, defined as {conv3×3, conv1×3, conv3×1, identity}. As the 1×3 and 3×1 convolutions have asymmetric kernels and oriented structure priors, they may help to capture the features of extreme aspect-ratio and rotated text lines.
+
+TextNet is the backbone for Fast, but can also be used as an efficient text/image classification, we add a `TextNetForImageClassification` as is it would allow people to train an image classifier on top of the pre-trained textnet weights
+
+## TextNetConfig
+
+[[autodoc]] TextNetConfig
+
+## TextNetImageProcessor
+
+[[autodoc]] TextNetImageProcessor
+ - preprocess
+
+## TextNetModel
+
+[[autodoc]] TextNetModel
+ - forward
+
+## TextNetForImageClassification
+
+[[autodoc]] TextNetForImageClassification
+ - forward
+
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/time_series_transformer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/time_series_transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..c5bfcfc15ea2a244d01bd5f94788a063200e394c
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/time_series_transformer.md
@@ -0,0 +1,72 @@
+
+
+# Time Series Transformer
+
+## Overview
+
+The Time Series Transformer model is a vanilla encoder-decoder Transformer for time series forecasting.
+This model was contributed by [kashif](https://huggingface.co/kashif).
+
+## Usage tips
+
+- Similar to other models in the library, [`TimeSeriesTransformerModel`] is the raw Transformer without any head on top, and [`TimeSeriesTransformerForPrediction`]
+adds a distribution head on top of the former, which can be used for time-series forecasting. Note that this is a so-called probabilistic forecasting model, not a
+point forecasting model. This means that the model learns a distribution, from which one can sample. The model doesn't directly output values.
+- [`TimeSeriesTransformerForPrediction`] consists of 2 blocks: an encoder, which takes a `context_length` of time series values as input (called `past_values`),
+and a decoder, which predicts a `prediction_length` of time series values into the future (called `future_values`). During training, one needs to provide
+pairs of (`past_values` and `future_values`) to the model.
+- In addition to the raw (`past_values` and `future_values`), one typically provides additional features to the model. These can be the following:
+ - `past_time_features`: temporal features which the model will add to `past_values`. These serve as "positional encodings" for the Transformer encoder.
+ Examples are "day of the month", "month of the year", etc. as scalar values (and then stacked together as a vector).
+ e.g. if a given time-series value was obtained on the 11th of August, then one could have [11, 8] as time feature vector (11 being "day of the month", 8 being "month of the year").
+ - `future_time_features`: temporal features which the model will add to `future_values`. These serve as "positional encodings" for the Transformer decoder.
+ Examples are "day of the month", "month of the year", etc. as scalar values (and then stacked together as a vector).
+ e.g. if a given time-series value was obtained on the 11th of August, then one could have [11, 8] as time feature vector (11 being "day of the month", 8 being "month of the year").
+ - `static_categorical_features`: categorical features which are static over time (i.e., have the same value for all `past_values` and `future_values`).
+ An example here is the store ID or region ID that identifies a given time-series.
+ Note that these features need to be known for ALL data points (also those in the future).
+ - `static_real_features`: real-valued features which are static over time (i.e., have the same value for all `past_values` and `future_values`).
+ An example here is the image representation of the product for which you have the time-series values (like the [ResNet](resnet) embedding of a "shoe" picture,
+ if your time-series is about the sales of shoes).
+ Note that these features need to be known for ALL data points (also those in the future).
+- The model is trained using "teacher-forcing", similar to how a Transformer is trained for machine translation. This means that, during training, one shifts the
+`future_values` one position to the right as input to the decoder, prepended by the last value of `past_values`. At each time step, the model needs to predict the
+next target. So the set-up of training is similar to a GPT model for language, except that there's no notion of `decoder_start_token_id` (we just use the last value
+of the context as initial input for the decoder).
+- At inference time, we give the final value of the `past_values` as input to the decoder. Next, we can sample from the model to make a prediction at the next time step,
+which is then fed to the decoder in order to make the next prediction (also called autoregressive generation).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Check out the Time Series Transformer blog-post in HuggingFace blog: [Probabilistic Time Series Forecasting with 🤗 Transformers](https://huggingface.co/blog/time-series-transformers)
+
+
+## TimeSeriesTransformerConfig
+
+[[autodoc]] TimeSeriesTransformerConfig
+
+## TimeSeriesTransformerModel
+
+[[autodoc]] TimeSeriesTransformerModel
+ - forward
+
+## TimeSeriesTransformerForPrediction
+
+[[autodoc]] TimeSeriesTransformerForPrediction
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/timesformer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/timesformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..fe75bee5b2897eb1dfb4bbb28fd7d5534083db9a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/timesformer.md
@@ -0,0 +1,52 @@
+
+
+# TimeSformer
+
+## Overview
+
+The TimeSformer model was proposed in [TimeSformer: Is Space-Time Attention All You Need for Video Understanding?](https://arxiv.org/abs/2102.05095) by Facebook Research.
+This work is a milestone in action-recognition field being the first video transformer. It inspired many transformer based video understanding and classification papers.
+
+The abstract from the paper is the following:
+
+*We present a convolution-free approach to video classification built exclusively on self-attention over space and time. Our method, named "TimeSformer," adapts the standard Transformer architecture to video by enabling spatiotemporal feature learning directly from a sequence of frame-level patches. Our experimental study compares different self-attention schemes and suggests that "divided attention," where temporal attention and spatial attention are separately applied within each block, leads to the best video classification accuracy among the design choices considered. Despite the radically new design, TimeSformer achieves state-of-the-art results on several action recognition benchmarks, including the best reported accuracy on Kinetics-400 and Kinetics-600. Finally, compared to 3D convolutional networks, our model is faster to train, it can achieve dramatically higher test efficiency (at a small drop in accuracy), and it can also be applied to much longer video clips (over one minute long). Code and models are available at: [this https URL](https://github.com/facebookresearch/TimeSformer).*
+
+This model was contributed by [fcakyon](https://huggingface.co/fcakyon).
+The original code can be found [here](https://github.com/facebookresearch/TimeSformer).
+
+## Usage tips
+
+There are many pretrained variants. Select your pretrained model based on the dataset it is trained on. Moreover,
+the number of input frames per clip changes based on the model size so you should consider this parameter while selecting your pretrained model.
+
+## Resources
+
+- [Video classification task guide](../tasks/video_classification)
+
+## TimesformerConfig
+
+[[autodoc]] TimesformerConfig
+
+## TimesformerModel
+
+[[autodoc]] TimesformerModel
+ - forward
+
+## TimesformerForVideoClassification
+
+[[autodoc]] TimesformerForVideoClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/timm_wrapper.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/timm_wrapper.md
new file mode 100644
index 0000000000000000000000000000000000000000..5af3d51746c325cc9085076fdfc8feaaa1ddb350
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/timm_wrapper.md
@@ -0,0 +1,67 @@
+
+
+# TimmWrapper
+
+## Overview
+
+Helper class to enable loading timm models to be used with the transformers library and its autoclasses.
+
+```python
+>>> import torch
+>>> from PIL import Image
+>>> from urllib.request import urlopen
+>>> from transformers import AutoModelForImageClassification, AutoImageProcessor
+
+>>> # Load image
+>>> image = Image.open(urlopen(
+... 'https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/beignets-task-guide.png'
+... ))
+
+>>> # Load model and image processor
+>>> checkpoint = "timm/resnet50.a1_in1k"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
+>>> model = AutoModelForImageClassification.from_pretrained(checkpoint).eval()
+
+>>> # Preprocess image
+>>> inputs = image_processor(image)
+
+>>> # Forward pass
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+
+>>> # Get top 5 predictions
+>>> top5_probabilities, top5_class_indices = torch.topk(logits.softmax(dim=1) * 100, k=5)
+```
+
+## TimmWrapperConfig
+
+[[autodoc]] TimmWrapperConfig
+
+## TimmWrapperImageProcessor
+
+[[autodoc]] TimmWrapperImageProcessor
+ - preprocess
+
+## TimmWrapperModel
+
+[[autodoc]] TimmWrapperModel
+ - forward
+
+## TimmWrapperForImageClassification
+
+[[autodoc]] TimmWrapperForImageClassification
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/trajectory_transformer.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/trajectory_transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..45616255871a0807a023b31101af2685bd0685ae
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/trajectory_transformer.md
@@ -0,0 +1,61 @@
+
+
+# Trajectory Transformer
+
+
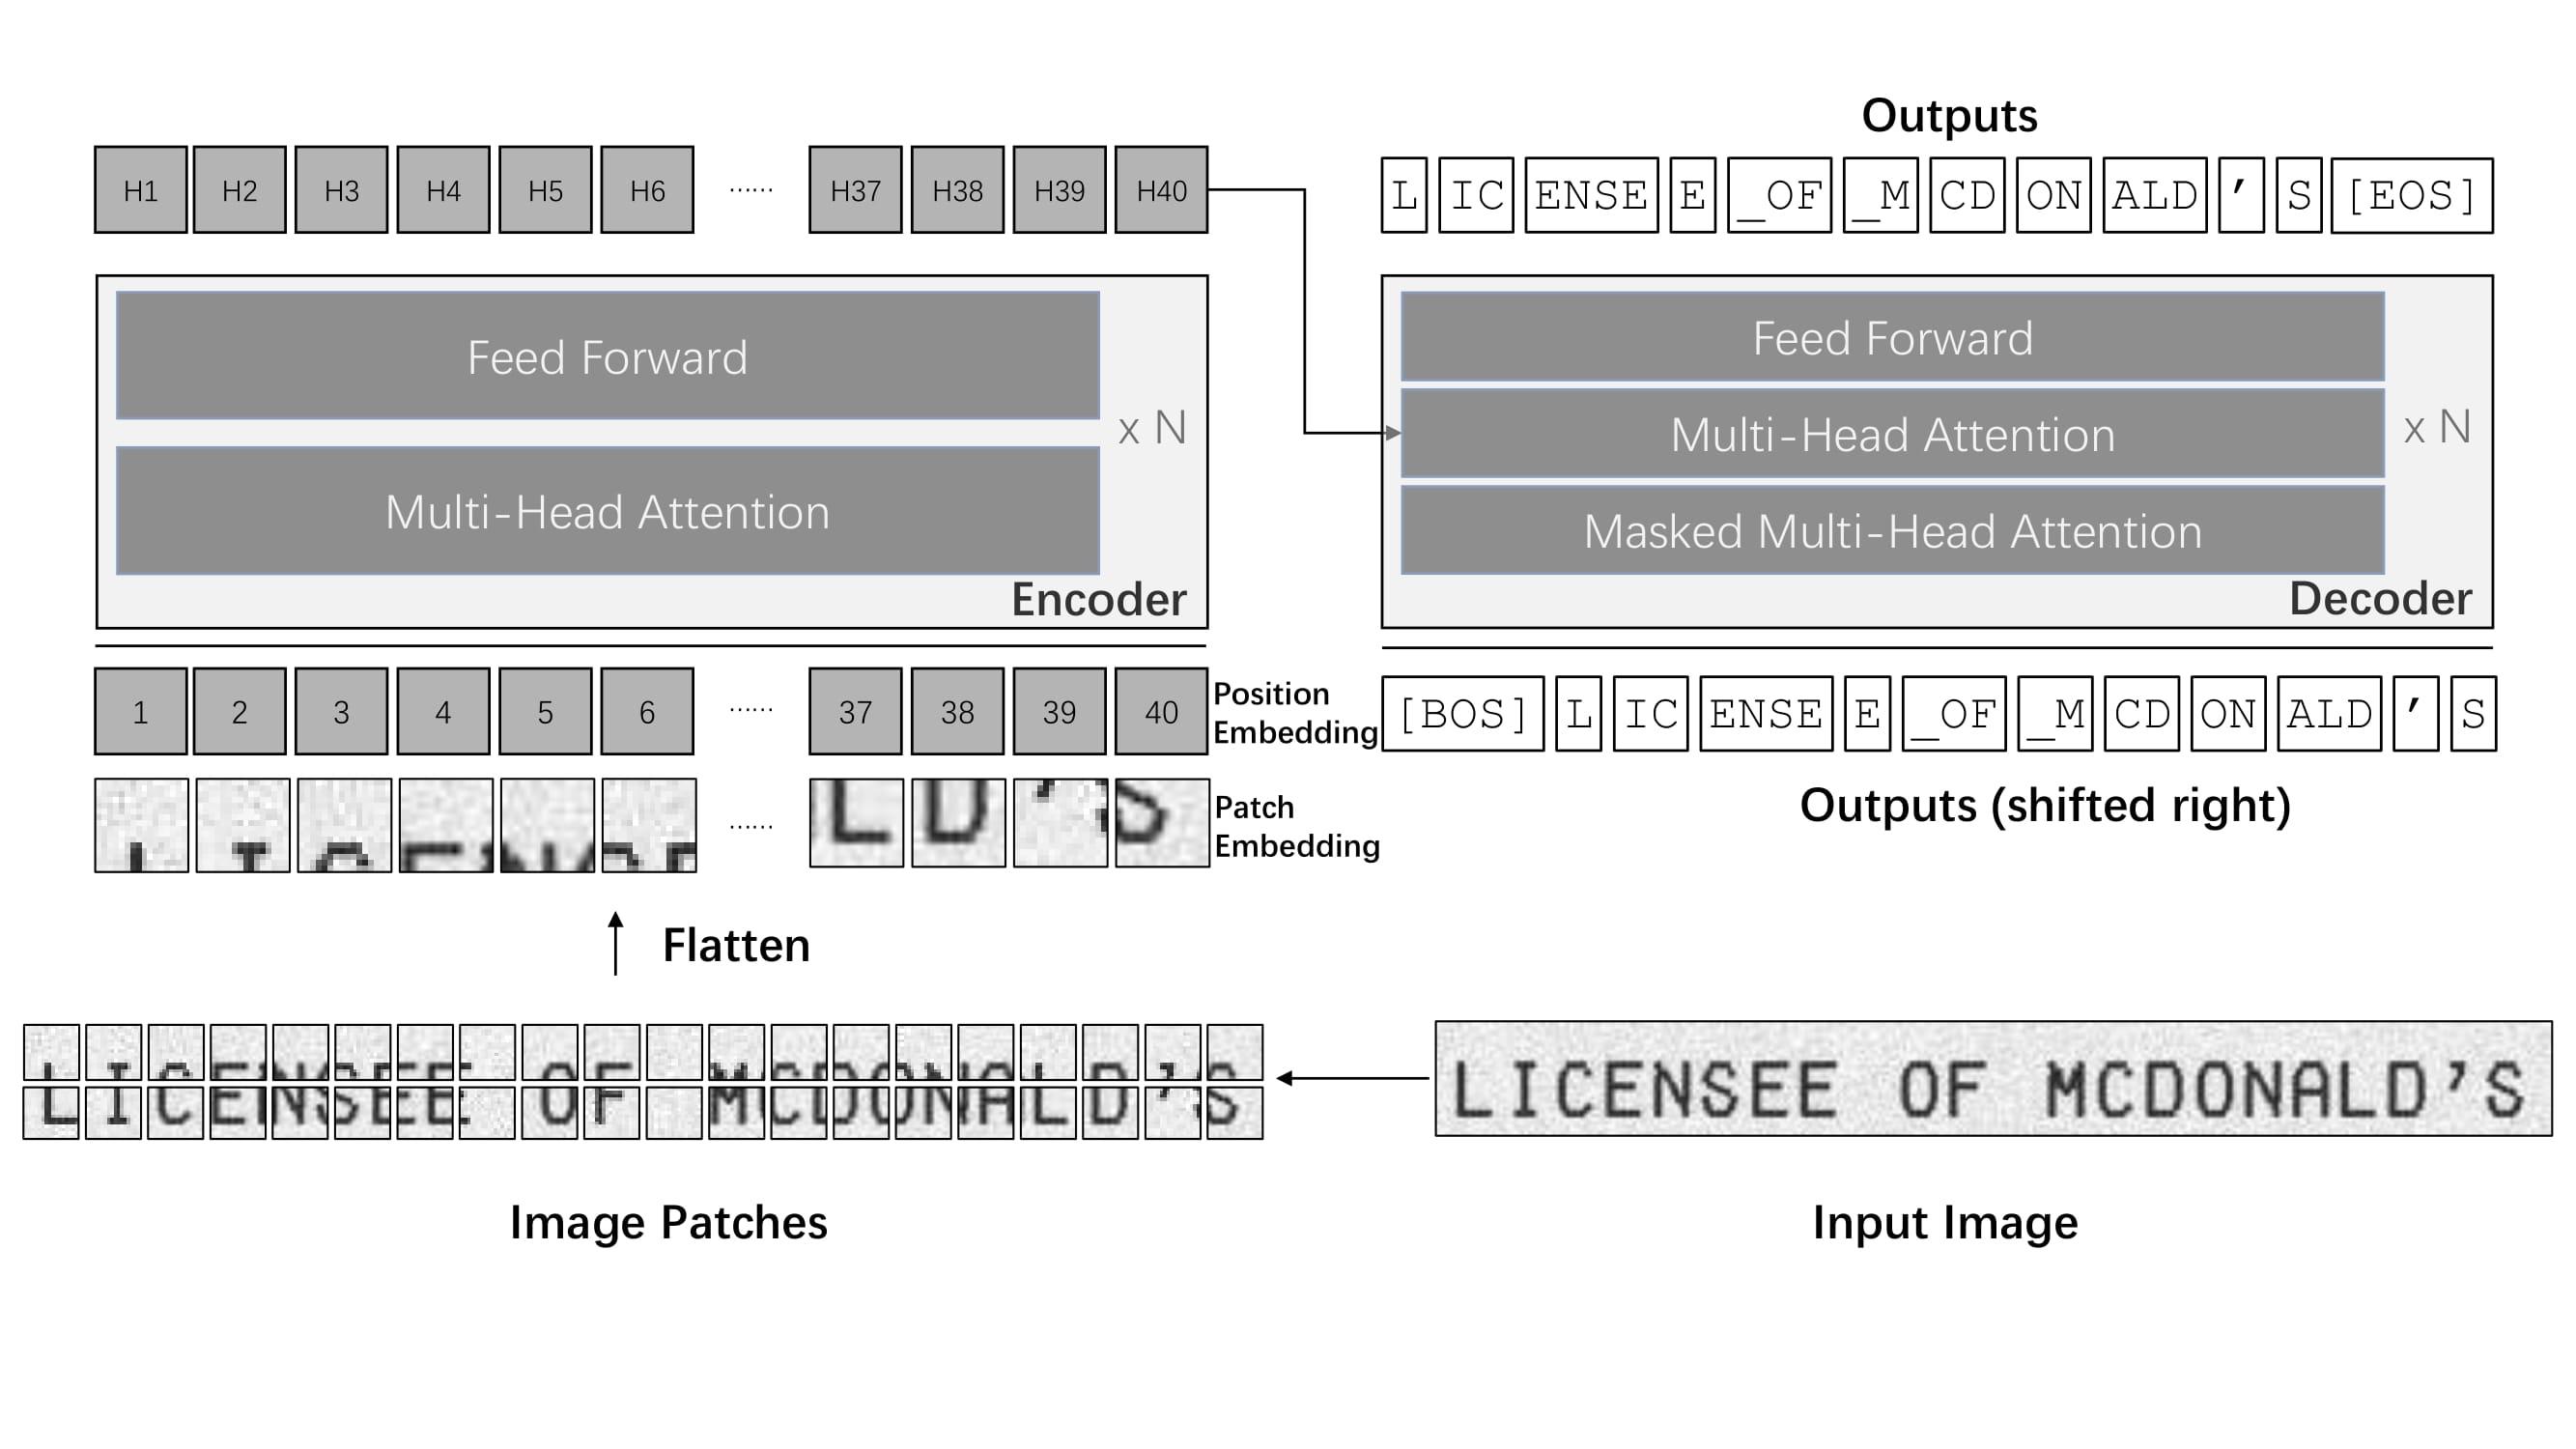 +
+ TrOCR architecture. Taken from the original paper.
+
+Please refer to the [`VisionEncoderDecoder`] class on how to use this model.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found
+[here](https://github.com/microsoft/unilm/tree/6f60612e7cc86a2a1ae85c47231507a587ab4e01/trocr).
+
+## Usage tips
+
+- The quickest way to get started with TrOCR is by checking the [tutorial
+ notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/TrOCR), which show how to use the model
+ at inference time as well as fine-tuning on custom data.
+- TrOCR is pre-trained in 2 stages before being fine-tuned on downstream datasets. It achieves state-of-the-art results
+ on both printed (e.g. the [SROIE dataset](https://paperswithcode.com/dataset/sroie) and handwritten (e.g. the [IAM
+ Handwriting dataset](https://fki.tic.heia-fr.ch/databases/iam-handwriting-database>) text recognition tasks. For more
+ information, see the [official models](https://huggingface.co/models?other=trocr>).
+- TrOCR is always used within the [VisionEncoderDecoder](vision-encoder-decoder) framework.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with TrOCR. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
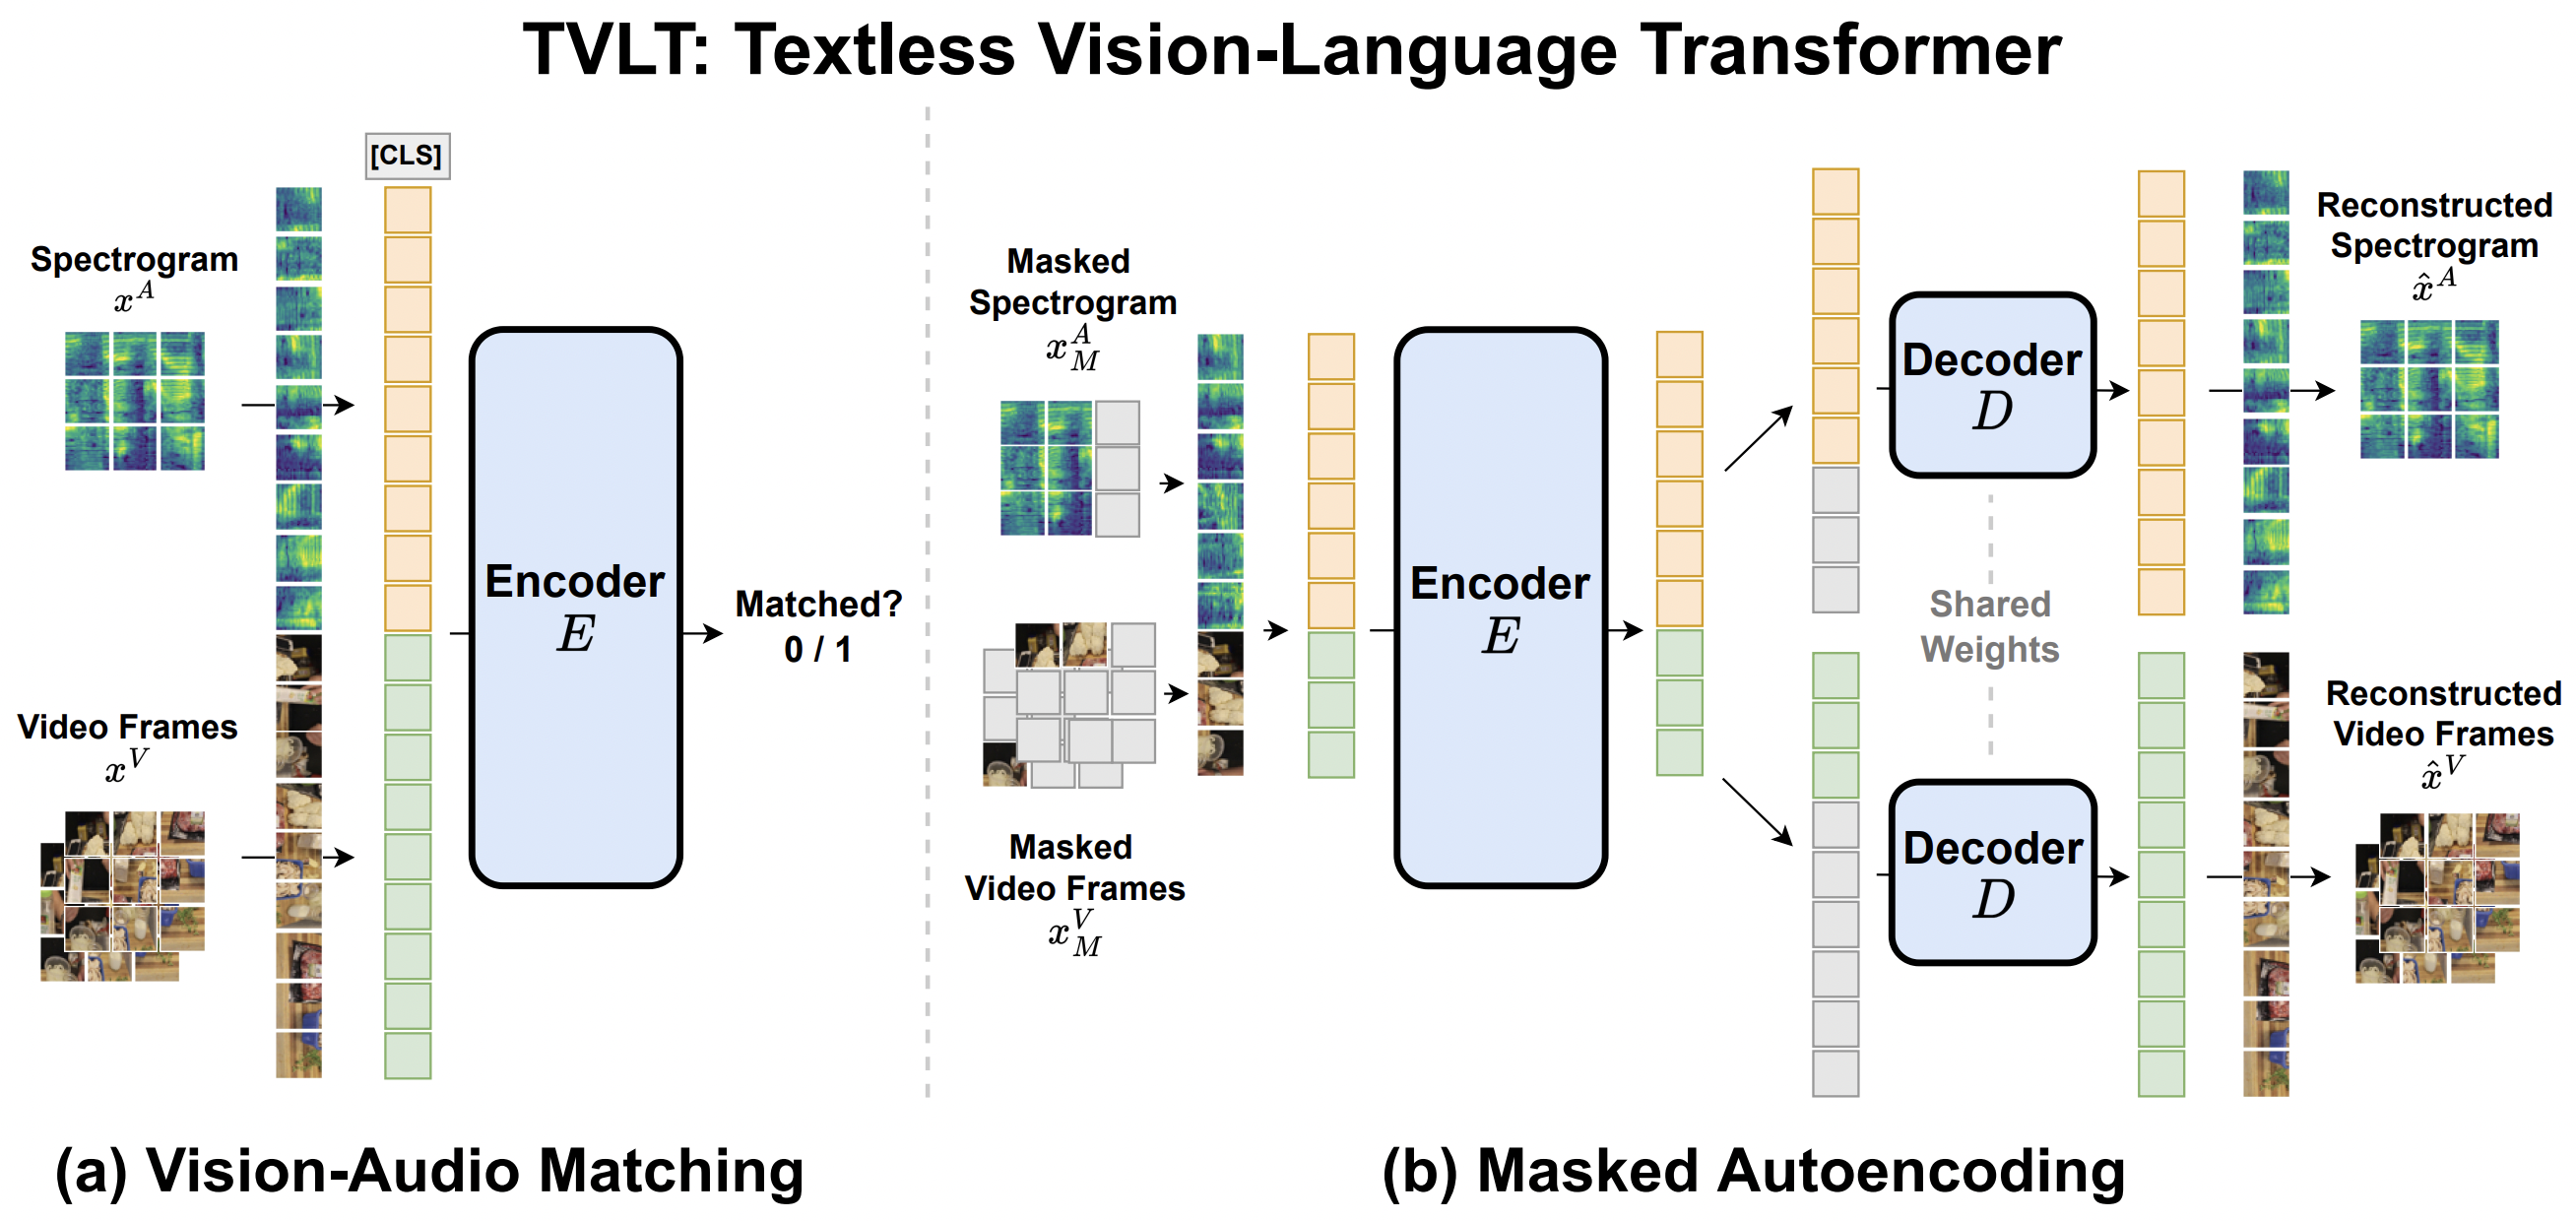 +
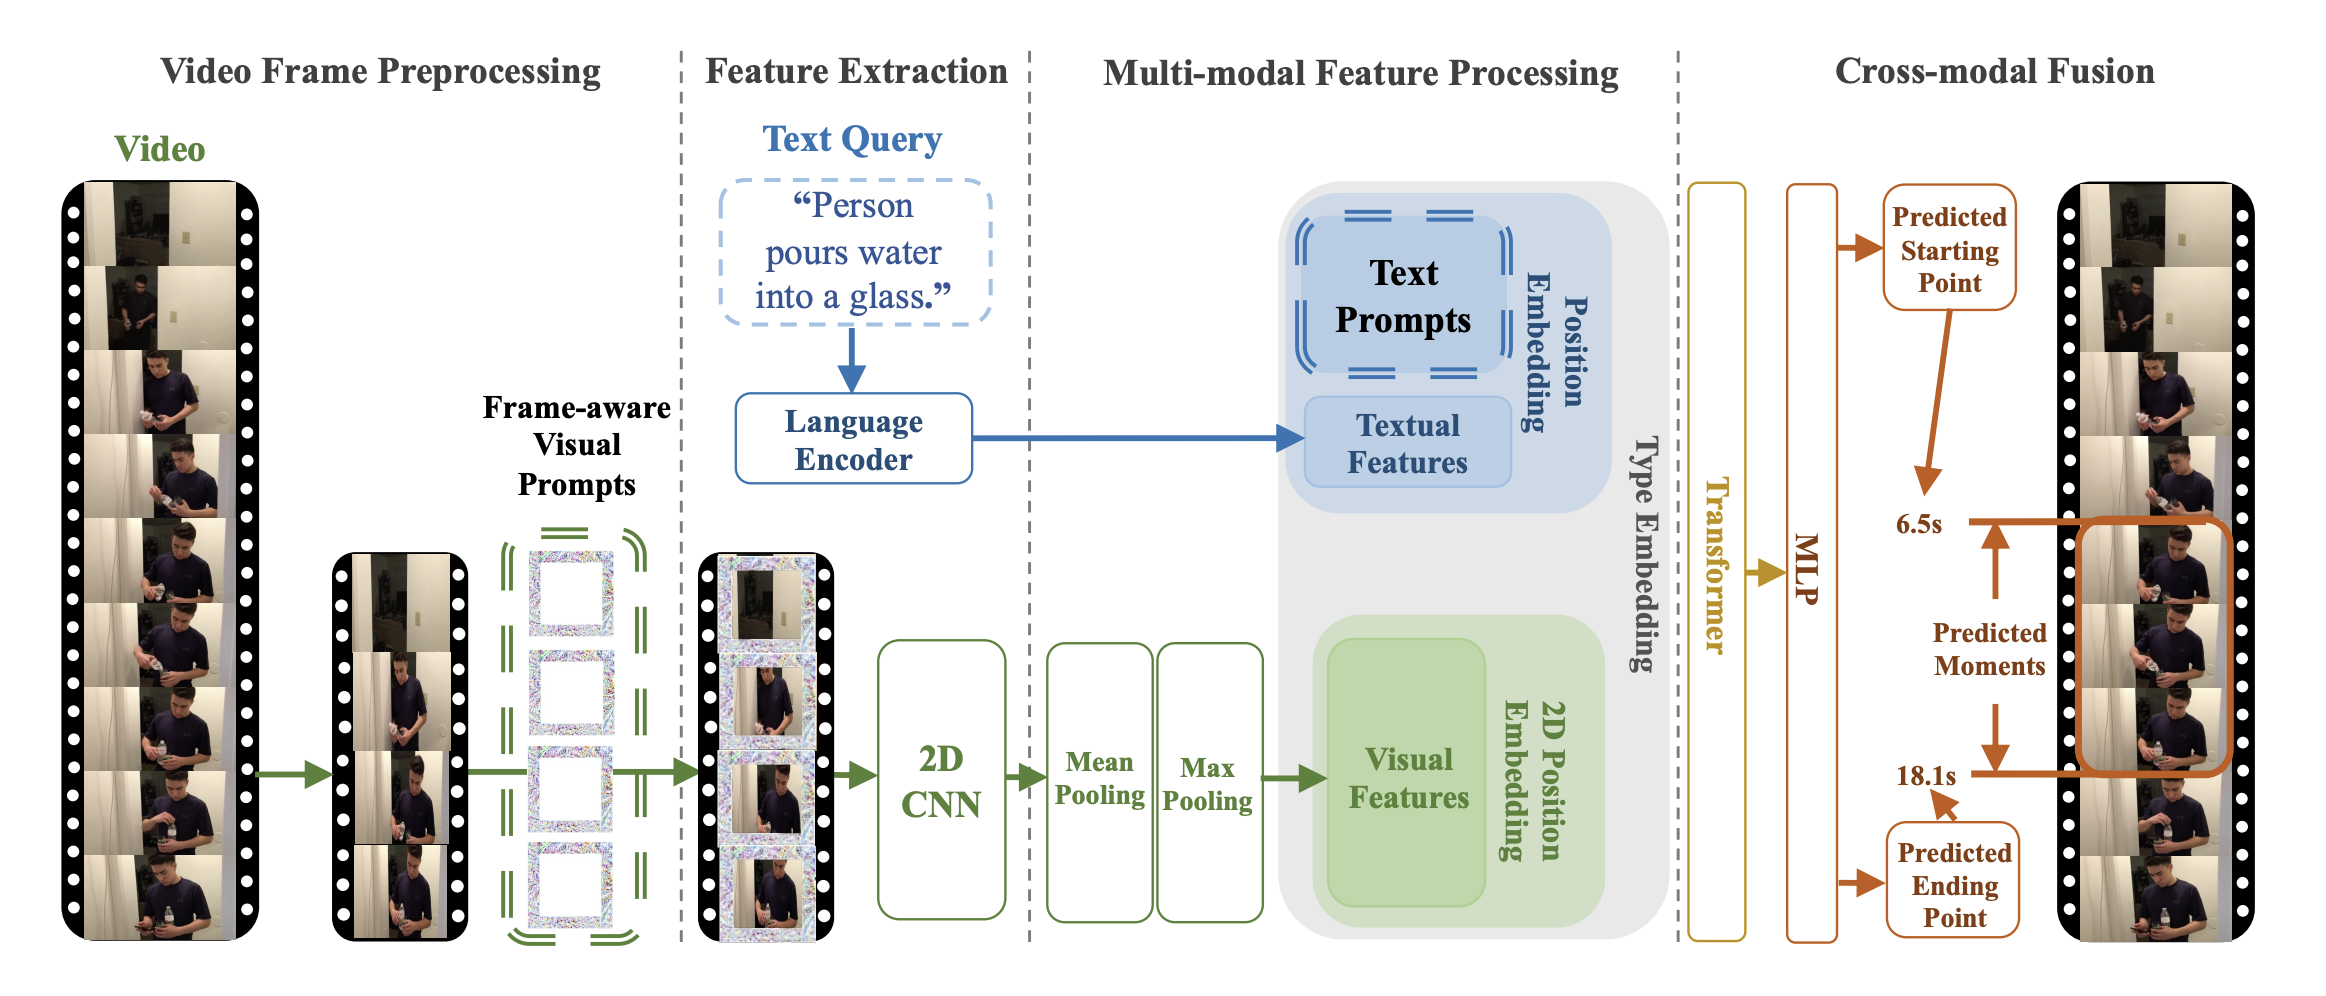 +
+ TVP architecture. Taken from the original paper.
+
+This model was contributed by [Jiqing Feng](https://huggingface.co/Jiqing). The original code can be found [here](https://github.com/intel/TVP).
+
+## Usage tips and examples
+
+Prompts are optimized perturbation patterns, which would be added to input video frames or text features. Universal set refers to using the same exact set of prompts for any input, this means that these prompts are added consistently to all video frames and text features, regardless of the input's content.
+
+TVP consists of a visual encoder and cross-modal encoder. A universal set of visual prompts and text prompts to be integrated into sampled video frames and textual features, respectively. Specially, a set of different visual prompts are applied to uniformly-sampled frames of one untrimmed video in order.
+
+The goal of this model is to incorporate trainable prompts into both visual inputs and textual features to temporal video grounding(TVG) problems.
+In principle, one can apply any visual, cross-modal encoder in the proposed architecture.
+
+The [`TvpProcessor`] wraps [`BertTokenizer`] and [`TvpImageProcessor`] into a single instance to both
+encode the text and prepare the images respectively.
+
+The following example shows how to run temporal video grounding using [`TvpProcessor`] and [`TvpForVideoGrounding`].
+```python
+import av
+import cv2
+import numpy as np
+import torch
+from huggingface_hub import hf_hub_download
+from transformers import AutoProcessor, TvpForVideoGrounding
+
+
+def pyav_decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps):
+ '''
+ Convert the video from its original fps to the target_fps and decode the video with PyAV decoder.
+ Args:
+ container (container): pyav container.
+ sampling_rate (int): frame sampling rate (interval between two sampled frames).
+ num_frames (int): number of frames to sample.
+ clip_idx (int): if clip_idx is -1, perform random temporal sampling.
+ If clip_idx is larger than -1, uniformly split the video to num_clips
+ clips, and select the clip_idx-th video clip.
+ num_clips (int): overall number of clips to uniformly sample from the given video.
+ target_fps (int): the input video may have different fps, convert it to
+ the target video fps before frame sampling.
+ Returns:
+ frames (tensor): decoded frames from the video. Return None if the no
+ video stream was found.
+ fps (float): the number of frames per second of the video.
+ '''
+ video = container.streams.video[0]
+ fps = float(video.average_rate)
+ clip_size = sampling_rate * num_frames / target_fps * fps
+ delta = max(num_frames - clip_size, 0)
+ start_idx = delta * clip_idx / num_clips
+ end_idx = start_idx + clip_size - 1
+ timebase = video.duration / num_frames
+ video_start_pts = int(start_idx * timebase)
+ video_end_pts = int(end_idx * timebase)
+ seek_offset = max(video_start_pts - 1024, 0)
+ container.seek(seek_offset, any_frame=False, backward=True, stream=video)
+ frames = {}
+ for frame in container.decode(video=0):
+ if frame.pts < video_start_pts:
+ continue
+ frames[frame.pts] = frame
+ if frame.pts > video_end_pts:
+ break
+ frames = [frames[pts] for pts in sorted(frames)]
+ return frames, fps
+
+
+def decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps):
+ '''
+ Decode the video and perform temporal sampling.
+ Args:
+ container (container): pyav container.
+ sampling_rate (int): frame sampling rate (interval between two sampled frames).
+ num_frames (int): number of frames to sample.
+ clip_idx (int): if clip_idx is -1, perform random temporal sampling.
+ If clip_idx is larger than -1, uniformly split the video to num_clips
+ clips, and select the clip_idx-th video clip.
+ num_clips (int): overall number of clips to uniformly sample from the given video.
+ target_fps (int): the input video may have different fps, convert it to
+ the target video fps before frame sampling.
+ Returns:
+ frames (tensor): decoded frames from the video.
+ '''
+ assert clip_idx >= -2, "Not a valied clip_idx {}".format(clip_idx)
+ frames, fps = pyav_decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps)
+ clip_size = sampling_rate * num_frames / target_fps * fps
+ index = np.linspace(0, clip_size - 1, num_frames)
+ index = np.clip(index, 0, len(frames) - 1).astype(np.int64)
+ frames = np.array([frames[idx].to_rgb().to_ndarray() for idx in index])
+ frames = frames.transpose(0, 3, 1, 2)
+ return frames
+
+
+file = hf_hub_download(repo_id="Intel/tvp_demo", filename="AK2KG.mp4", repo_type="dataset")
+model = TvpForVideoGrounding.from_pretrained("Intel/tvp-base")
+
+decoder_kwargs = dict(
+ container=av.open(file, metadata_errors="ignore"),
+ sampling_rate=1,
+ num_frames=model.config.num_frames,
+ clip_idx=0,
+ num_clips=1,
+ target_fps=3,
+)
+raw_sampled_frms = decode(**decoder_kwargs)
+
+text = "a person is sitting on a bed."
+processor = AutoProcessor.from_pretrained("Intel/tvp-base")
+model_inputs = processor(
+ text=[text], videos=list(raw_sampled_frms), return_tensors="pt", max_text_length=100#, size=size
+)
+
+model_inputs["pixel_values"] = model_inputs["pixel_values"].to(model.dtype)
+output = model(**model_inputs)
+
+def get_video_duration(filename):
+ cap = cv2.VideoCapture(filename)
+ if cap.isOpened():
+ rate = cap.get(5)
+ frame_num = cap.get(7)
+ duration = frame_num/rate
+ return duration
+ return -1
+
+duration = get_video_duration(file)
+start, end = processor.post_process_video_grounding(output.logits, duration)
+
+print(f"The time slot of the video corresponding to the text \"{text}\" is from {start}s to {end}s")
+```
+
+Tips:
+
+- This implementation of TVP uses [`BertTokenizer`] to generate text embeddings and Resnet-50 model to compute visual embeddings.
+- Checkpoints for pre-trained [tvp-base](https://huggingface.co/Intel/tvp-base) is released.
+- Please refer to [Table 2](https://arxiv.org/pdf/2303.04995.pdf) for TVP's performance on Temporal Video Grounding task.
+
+
+## TvpConfig
+
+[[autodoc]] TvpConfig
+
+## TvpImageProcessor
+
+[[autodoc]] TvpImageProcessor
+ - preprocess
+
+## TvpProcessor
+
+[[autodoc]] TvpProcessor
+ - __call__
+
+## TvpModel
+
+[[autodoc]] TvpModel
+ - forward
+
+## TvpForVideoGrounding
+
+[[autodoc]] TvpForVideoGrounding
+ - forward
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/udop.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/udop.md
new file mode 100644
index 0000000000000000000000000000000000000000..614bd2ff4fd7156e094b83f20dfb4a76bf32a4cf
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/udop.md
@@ -0,0 +1,113 @@
+
+
+# UDOP
+
+## Overview
+
+The UDOP model was proposed in [Unifying Vision, Text, and Layout for Universal Document Processing](https://arxiv.org/abs/2212.02623) by Zineng Tang, Ziyi Yang, Guoxin Wang, Yuwei Fang, Yang Liu, Chenguang Zhu, Michael Zeng, Cha Zhang, Mohit Bansal.
+UDOP adopts an encoder-decoder Transformer architecture based on [T5](t5) for document AI tasks like document image classification, document parsing and document visual question answering.
+
+The abstract from the paper is the following:
+
+We propose Universal Document Processing (UDOP), a foundation Document AI model which unifies text, image, and layout modalities together with varied task formats, including document understanding and generation. UDOP leverages the spatial correlation between textual content and document image to model image, text, and layout modalities with one uniform representation. With a novel Vision-Text-Layout Transformer, UDOP unifies pretraining and multi-domain downstream tasks into a prompt-based sequence generation scheme. UDOP is pretrained on both large-scale unlabeled document corpora using innovative self-supervised objectives and diverse labeled data. UDOP also learns to generate document images from text and layout modalities via masked image reconstruction. To the best of our knowledge, this is the first time in the field of document AI that one model simultaneously achieves high-quality neural document editing and content customization. Our method sets the state-of-the-art on 9 Document AI tasks, e.g., document understanding and QA, across diverse data domains like finance reports, academic papers, and websites. UDOP ranks first on the leaderboard of the Document Understanding Benchmark (DUE).*
+
+
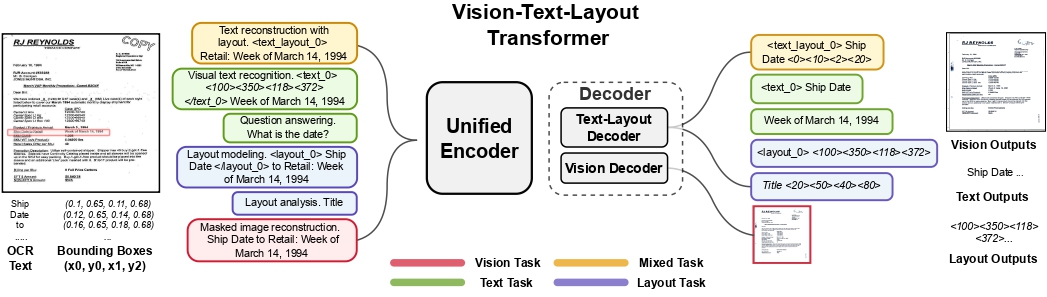 +
+ UDOP architecture. Taken from the original paper.
+
+## Usage tips
+
+- In addition to *input_ids*, [`UdopForConditionalGeneration`] also expects the input `bbox`, which are
+ the bounding boxes (i.e. 2D-positions) of the input tokens. These can be obtained using an external OCR engine such
+ as Google's [Tesseract](https://github.com/tesseract-ocr/tesseract) (there's a [Python wrapper](https://pypi.org/project/pytesseract/) available). Each bounding box should be in (x0, y0, x1, y1) format, where (x0, y0) corresponds to the position of the upper left corner in the bounding box, and (x1, y1) represents the
+ position of the lower right corner. Note that one first needs to normalize the bounding boxes to be on a 0-1000
+ scale. To normalize, you can use the following function:
+
+```python
+def normalize_bbox(bbox, width, height):
+ return [
+ int(1000 * (bbox[0] / width)),
+ int(1000 * (bbox[1] / height)),
+ int(1000 * (bbox[2] / width)),
+ int(1000 * (bbox[3] / height)),
+ ]
+```
+
+Here, `width` and `height` correspond to the width and height of the original document in which the token
+occurs. Those can be obtained using the Python Image Library (PIL) library for example, as follows:
+
+```python
+from PIL import Image
+
+# Document can be a png, jpg, etc. PDFs must be converted to images.
+image = Image.open(name_of_your_document).convert("RGB")
+
+width, height = image.size
+```
+
+One can use [`UdopProcessor`] to prepare images and text for the model, which takes care of all of this. By default, this class uses the Tesseract engine to extract a list of words and boxes (coordinates) from a given document. Its functionality is equivalent to that of [`LayoutLMv3Processor`], hence it supports passing either `apply_ocr=False` in case you prefer to use your own OCR engine or `apply_ocr=True` in case you want the default OCR engine to be used. Refer to the [usage guide of LayoutLMv2](layoutlmv2#usage-layoutlmv2processor) regarding all possible use cases (the functionality of `UdopProcessor` is identical).
+
+- If using an own OCR engine of choice, one recommendation is Azure's [Read API](https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/how-to/call-read-api), which supports so-called line segments. Use of segment position embeddings typically results in better performance.
+- At inference time, it's recommended to use the `generate` method to autoregressively generate text given a document image.
+- The model has been pre-trained on both self-supervised and supervised objectives. One can use the various task prefixes (prompts) used during pre-training to test out the out-of-the-box capabilities. For instance, the model can be prompted with "Question answering. What is the date?", as "Question answering." is the task prefix used during pre-training for DocVQA. Refer to the [paper](https://arxiv.org/abs/2212.02623) (table 1) for all task prefixes.
+- One can also fine-tune [`UdopEncoderModel`], which is the encoder-only part of UDOP, which can be seen as a LayoutLMv3-like Transformer encoder. For discriminative tasks, one can just add a linear classifier on top of it and fine-tune it on a labeled dataset.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/microsoft/UDOP).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with UDOP. If
+you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll
+review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Demo notebooks regarding UDOP can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/UDOP) that show how
+to fine-tune UDOP on a custom dataset as well as inference. 🌎
+- [Document question answering task guide](../tasks/document_question_answering)
+
+## UdopConfig
+
+[[autodoc]] UdopConfig
+
+## UdopTokenizer
+
+[[autodoc]] UdopTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## UdopTokenizerFast
+
+[[autodoc]] UdopTokenizerFast
+
+## UdopProcessor
+
+[[autodoc]] UdopProcessor
+ - __call__
+
+## UdopModel
+
+[[autodoc]] UdopModel
+ - forward
+
+## UdopForConditionalGeneration
+
+[[autodoc]] UdopForConditionalGeneration
+ - forward
+
+## UdopEncoderModel
+
+[[autodoc]] UdopEncoderModel
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/ul2.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/ul2.md
new file mode 100644
index 0000000000000000000000000000000000000000..f4d01c40b0c10944e5ddb3451f355e4c95bf2d9a
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/ul2.md
@@ -0,0 +1,43 @@
+
+
+# UL2
+
+## Overview
+
+The T5 model was presented in [Unifying Language Learning Paradigms](https://arxiv.org/pdf/2205.05131v1.pdf) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler.
+
+The abstract from the paper is the following:
+
+*Existing pre-trained models are generally geared towards a particular class of problems. To date, there seems to be still no consensus on what the right architecture and pre-training setup should be. This paper presents a unified framework for pre-training models that are universally effective across datasets and setups. We begin by disentangling architectural archetypes with pre-training objectives -- two concepts that are commonly conflated. Next, we present a generalized and unified perspective for self-supervision in NLP and show how different pre-training objectives can be cast as one another and how interpolating between different objectives can be effective. We then propose Mixture-of-Denoisers (MoD), a pre-training objective that combines diverse pre-training paradigms together. We furthermore introduce a notion of mode switching, wherein downstream fine-tuning is associated with specific pre-training schemes. We conduct extensive ablative experiments to compare multiple pre-training objectives and find that our method pushes the Pareto-frontier by outperforming T5 and/or GPT-like models across multiple diverse setups. Finally, by scaling our model up to 20B parameters, we achieve SOTA performance on 50 well-established supervised NLP tasks ranging from language generation (with automated and human evaluation), language understanding, text classification, question answering, commonsense reasoning, long text reasoning, structured knowledge grounding and information retrieval. Our model also achieve strong results at in-context learning, outperforming 175B GPT-3 on zero-shot SuperGLUE and tripling the performance of T5-XXL on one-shot summarization.*
+
+This model was contributed by [DanielHesslow](https://huggingface.co/Seledorn). The original code can be found [here](https://github.com/google-research/google-research/tree/master/ul2).
+
+## Usage tips
+
+- UL2 is an encoder-decoder model pre-trained on a mixture of denoising functions as well as fine-tuned on an array of downstream tasks.
+- UL2 has the same architecture as [T5v1.1](t5v1.1) but uses the Gated-SiLU activation function instead of Gated-GELU.
+- The authors release checkpoints of one architecture which can be seen [here](https://huggingface.co/google/ul2)
+
+
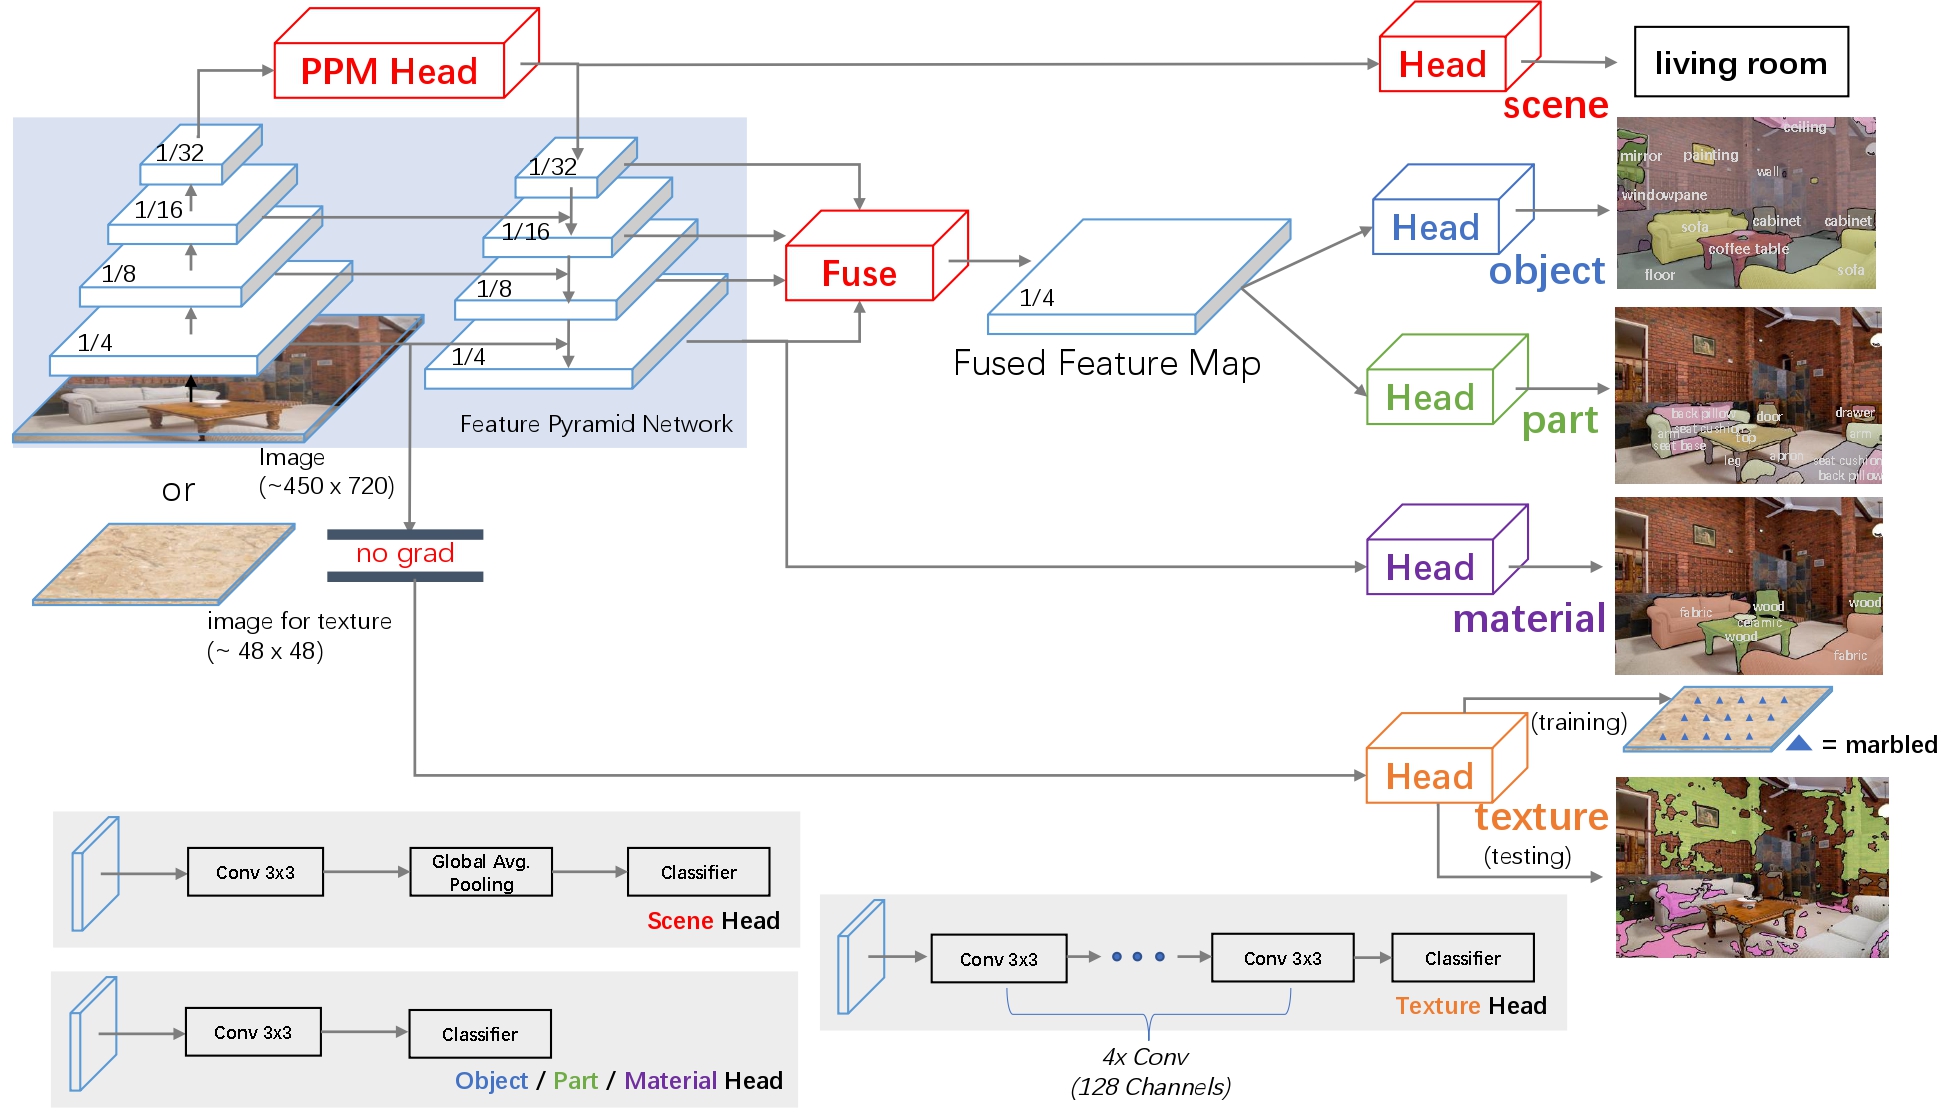 +
+ UPerNet framework. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code is based on OpenMMLab's mmsegmentation [here](https://github.com/open-mmlab/mmsegmentation/blob/master/mmseg/models/decode_heads/uper_head.py).
+
+## Usage examples
+
+UPerNet is a general framework for semantic segmentation. It can be used with any vision backbone, like so:
+
+```py
+from transformers import SwinConfig, UperNetConfig, UperNetForSemanticSegmentation
+
+backbone_config = SwinConfig(out_features=["stage1", "stage2", "stage3", "stage4"])
+
+config = UperNetConfig(backbone_config=backbone_config)
+model = UperNetForSemanticSegmentation(config)
+```
+
+To use another vision backbone, like [ConvNeXt](convnext), simply instantiate the model with the appropriate backbone:
+
+```py
+from transformers import ConvNextConfig, UperNetConfig, UperNetForSemanticSegmentation
+
+backbone_config = ConvNextConfig(out_features=["stage1", "stage2", "stage3", "stage4"])
+
+config = UperNetConfig(backbone_config=backbone_config)
+model = UperNetForSemanticSegmentation(config)
+```
+
+Note that this will randomly initialize all the weights of the model.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with UPerNet.
+
+- Demo notebooks for UPerNet can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/UPerNet).
+- [`UperNetForSemanticSegmentation`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/semantic-segmentation) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/semantic_segmentation.ipynb).
+- See also: [Semantic segmentation task guide](../tasks/semantic_segmentation)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## UperNetConfig
+
+[[autodoc]] UperNetConfig
+
+## UperNetForSemanticSegmentation
+
+[[autodoc]] UperNetForSemanticSegmentation
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/van.md b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/van.md
new file mode 100644
index 0000000000000000000000000000000000000000..2fb8475ce72f3285904df831617a8450d3300776
--- /dev/null
+++ b/tasks/tasksmith-333d8be2d5aa/tests/source/docs/source/en/model_doc/van.md
@@ -0,0 +1,72 @@
+
+
+# VAN
+
+
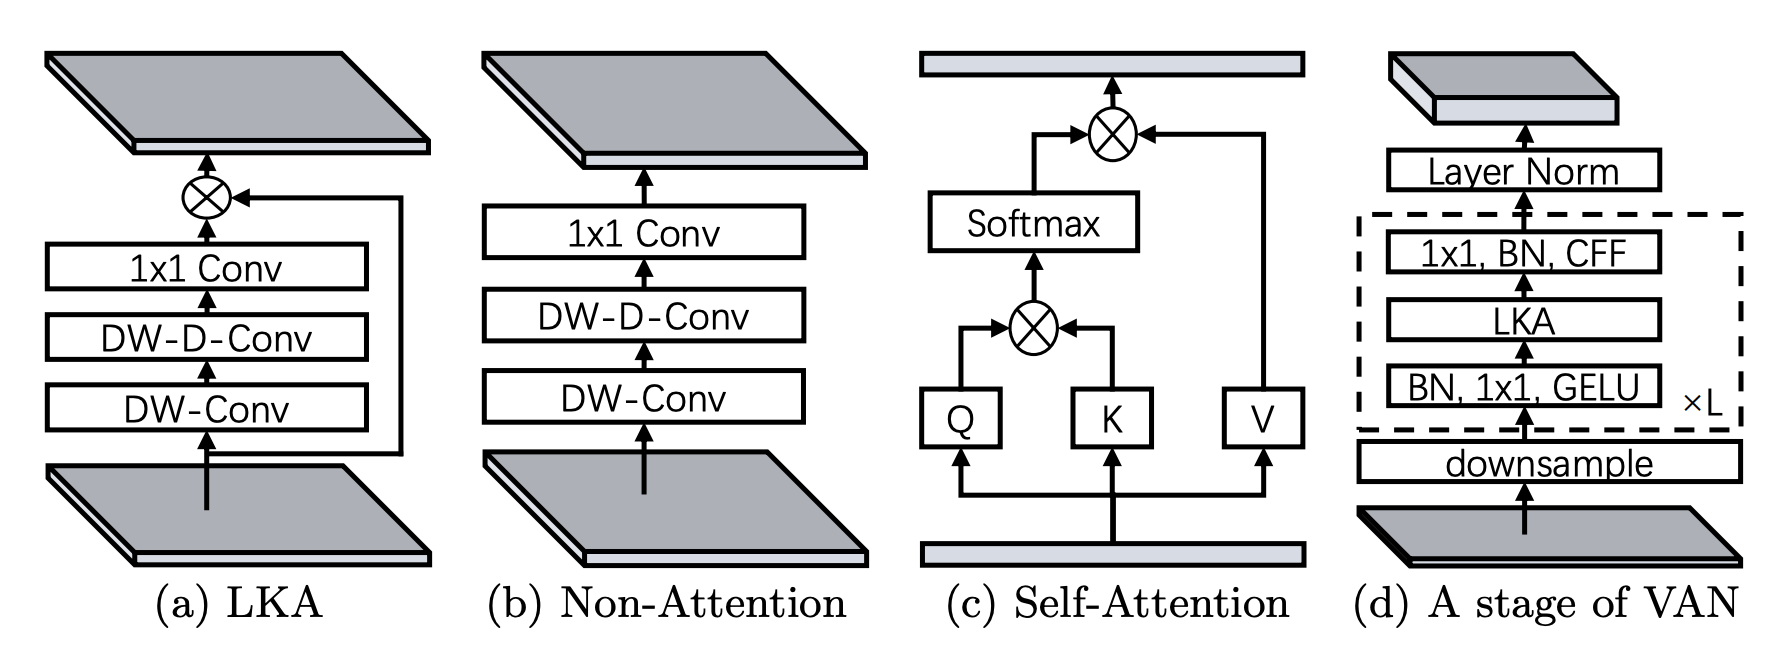 +
+This model was contributed by [Francesco](https://huggingface.co/Francesco). The original code can be found [here](https://github.com/Visual-Attention-Network/VAN-Classification).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with VAN.
+
+
 +
 +