+
+写真提供:[Denys Nevozhai](https://unsplash.com/@dnevozhai)。
+
+テキストおよび画像のプロンプトを単一のリストとしてモデルのプロセッサに渡し、適切な入力を作成できます。
+
+```py
+>>> prompt = [
+... "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
+... "This is an image of ",
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+This is an image of the Eiffel Tower in Paris, France.
+```
+
+## Few-shot prompting
+
+IDEFICS はゼロショットで優れた結果を示しますが、タスクによっては特定の形式のキャプションが必要になる場合や、キャプションが付属する場合があります。
+タスクの複雑さを増大させるその他の制限または要件。少数のショットのプロンプトを使用して、コンテキスト内の学習を有効にすることができます。
+プロンプトに例を指定することで、指定された例の形式を模倣した結果を生成するようにモデルを操作できます。
+
+前のエッフェル塔の画像をモデルの例として使用し、モデルにデモンストレーションするプロンプトを作成してみましょう。
+画像内のオブジェクトが何であるかを知ることに加えて、それに関する興味深い情報も取得したいと考えています。
+次に、自由の女神の画像に対して同じ応答形式を取得できるかどうかを見てみましょう。
+
+
+
+
+
+写真提供:[Juan Mayobre](https://unsplash.com/@jmayobres)。
+
+```py
+>>> prompt = ["User:",
+... "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
+... "Describe this image.\nAssistant: An image of the Eiffel Tower at night. Fun fact: the Eiffel Tower is the same height as an 81-storey building.\n",
+... "User:",
+... "https://images.unsplash.com/photo-1524099163253-32b7f0256868?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3387&q=80",
+... "Describe this image.\nAssistant:"
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=30, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+User: Describe this image.
+Assistant: An image of the Eiffel Tower at night. Fun fact: the Eiffel Tower is the same height as an 81-storey building.
+User: Describe this image.
+Assistant: An image of the Statue of Liberty. Fun fact: the Statue of Liberty is 151 feet tall.
+```
+
+モデルは 1 つの例 (つまり、1 ショット) だけからタスクの実行方法を学習していることに注目してください。より複雑なタスクの場合は、
+より多くの例 (3 ショット、5 ショットなど) を自由に試してみてください。
+
+## Visual question answering
+
+Visual Question Answering (VQA) は、画像に基づいて自由形式の質問に答えるタスクです。画像に似ている
+キャプションは、アクセシビリティ アプリケーションだけでなく、教育 (視覚資料についての推論) にも使用できます。
+サービス(画像を基にした商品に関する質問)、画像検索など。
+
+このタスク用に新しい画像を取得しましょう。
+
+
+
+
+
+写真提供 [Jarritos Mexican Soda](https://unsplash.com/@jarritos).
+
+適切な指示をプロンプトすることで、モデルを画像キャプションから視覚的な質問への応答に導くことができます。
+
+```py
+>>> prompt = [
+... "Instruction: Provide an answer to the question. Use the image to answer.\n",
+... "https://images.unsplash.com/photo-1623944889288-cd147dbb517c?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "Question: Where are these people and what's the weather like? Answer:"
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=20, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Provide an answer to the question. Use the image to answer.
+ Question: Where are these people and what's the weather like? Answer: They're in a park in New York City, and it's a beautiful day.
+```
+
+## Image classification
+
+IDEFICS は、次のデータを含むデータについて明示的にトレーニングしなくても、画像をさまざまなカテゴリに分類できます。
+これらの特定のカテゴリからのラベル付きの例。カテゴリのリストを指定し、その画像とテキストを使用して理解する
+機能を利用すると、モデルは画像がどのカテゴリに属する可能性が高いかを推測できます。
+
+たとえば、次のような野菜スタンドの画像があるとします。
+
+
+
+
+
+写真提供:[Peter Wendt](https://unsplash.com/@peterwendt)。
+
+画像を次のいずれかのカテゴリに分類するようにモデルに指示できます。
+
+```py
+>>> categories = ['animals','vegetables', 'city landscape', 'cars', 'office']
+>>> prompt = [f"Instruction: Classify the following image into a single category from the following list: {categories}.\n",
+... "https://images.unsplash.com/photo-1471193945509-9ad0617afabf?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "Category: "
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=6, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Classify the following image into a single category from the following list: ['animals', 'vegetables', 'city landscape', 'cars', 'office'].
+Category: Vegetables
+```
+
+上の例では、画像を 1 つのカテゴリに分類するようにモデルに指示していますが、ランク分類を行うようにモデルに指示することもできます。
+
+## Image-guided text generation
+
+よりクリエイティブなアプリケーションの場合は、画像ガイド付きテキスト生成を使用して、画像に基づいてテキストを生成できます。これは可能です
+製品、広告、シーンの説明などを作成するのに役立ちます。
+
+IDEFICS に、赤いドアの単純な画像に基づいてストーリーを書くように促してみましょう。
+
+
+
+
+
+写真提供:[Craig Tidball](https://unsplash.com/@devonshiremedia)。
+
+```py
+>>> prompt = ["Instruction: Use the image to write a story. \n",
+... "https://images.unsplash.com/photo-1517086822157-2b0358e7684a?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=2203&q=80",
+... "Story: \n"]
+
+>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, num_beams=2, max_new_tokens=200, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Use the image to write a story.
+ Story:
+Once upon a time, there was a little girl who lived in a house with a red door. She loved her red door. It was the prettiest door in the whole world.
+
+One day, the little girl was playing in her yard when she noticed a man standing on her doorstep. He was wearing a long black coat and a top hat.
+
+The little girl ran inside and told her mother about the man.
+
+Her mother said, “Don’t worry, honey. He’s just a friendly ghost.”
+
+The little girl wasn’t sure if she believed her mother, but she went outside anyway.
+
+When she got to the door, the man was gone.
+
+The next day, the little girl was playing in her yard again when she noticed the man standing on her doorstep.
+
+He was wearing a long black coat and a top hat.
+
+The little girl ran
+```
+
+IDEFICS は玄関先にあるカボチャに気づき、幽霊に関する不気味なハロウィーンの話をしたようです。
+
+
+
+このような長い出力の場合、テキスト生成戦略を微調整すると大きなメリットが得られます。これは役に立ちます
+生成される出力の品質が大幅に向上します。 [テキスト生成戦略](../generation_strategies) を確認してください。
+詳しく知ることができ。
+
+
+
+## Running inference in batch mode
+
+これまでのすべてのセクションでは、IDEFICS を 1 つの例として説明しました。非常に似た方法で、推論を実行できます。
+プロンプトのリストを渡すことにより、サンプルのバッチを取得します。
+
+```py
+>>> prompts = [
+... [ "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
+... "This is an image of ",
+... ],
+... [ "https://images.unsplash.com/photo-1623944889288-cd147dbb517c?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "This is an image of ",
+... ],
+... [ "https://images.unsplash.com/photo-1471193945509-9ad0617afabf?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "This is an image of ",
+... ],
+... ]
+
+>>> inputs = processor(prompts, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> for i,t in enumerate(generated_text):
+... print(f"{i}:\n{t}\n")
+0:
+This is an image of the Eiffel Tower in Paris, France.
+
+1:
+This is an image of a couple on a picnic blanket.
+
+2:
+This is an image of a vegetable stand.
+```
+
+## IDEFICS instruct for conversational use
+
+会話型のユースケースの場合は、🤗 ハブでモデルの微調整された指示されたバージョンを見つけることができます。
+`HuggingFaceM4/idefics-80b-instruct` および `HuggingFaceM4/idefics-9b-instruct`。
+
+これらのチェックポイントは、教師ありモデルと命令モデルを組み合わせたそれぞれの基本モデルを微調整した結果です。
+データセットを微調整することで、ダウンストリームのパフォーマンスを向上させながら、会話設定でモデルをより使いやすくします。
+
+会話での使用とプロンプトは、基本モデルの使用と非常に似ています。
+
+```py
+>>> import torch
+>>> from transformers import IdeficsForVisionText2Text, AutoProcessor
+
+>>> device = "cuda" if torch.cuda.is_available() else "cpu"
+
+>>> checkpoint = "HuggingFaceM4/idefics-9b-instruct"
+>>> model = IdeficsForVisionText2Text.from_pretrained(checkpoint, torch_dtype=torch.bfloat16).to(device)
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+
+>>> prompts = [
+... [
+... "User: What is in this image?",
+... "https://upload.wikimedia.org/wikipedia/commons/8/86/Id%C3%A9fix.JPG",
+... "",
+
+... "\nAssistant: This picture depicts Idefix, the dog of Obelix in Asterix and Obelix. Idefix is running on the ground.",
+
+... "\nUser:",
+... "https://static.wikia.nocookie.net/asterix/images/2/25/R22b.gif/revision/latest?cb=20110815073052",
+... "And who is that?",
+
+... "\nAssistant:",
+... ],
+... ]
+
+>>> # --batched mode
+>>> inputs = processor(prompts, add_end_of_utterance_token=False, return_tensors="pt").to(device)
+>>> # --single sample mode
+>>> # inputs = processor(prompts[0], return_tensors="pt").to(device)
+
+>>> # Generation args
+>>> exit_condition = processor.tokenizer("", add_special_tokens=False).input_ids
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, eos_token_id=exit_condition, bad_words_ids=bad_words_ids, max_length=100)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> for i, t in enumerate(generated_text):
+... print(f"{i}:\n{t}\n")
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/image_captioning.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/image_captioning.md
new file mode 100644
index 0000000000000000000000000000000000000000..7649947b2c6450110c60ad6f6d7f4a5ad2a9d49d
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/image_captioning.md
@@ -0,0 +1,276 @@
+
+
+# Image captioning
+
+[[open-in-colab]]
+
+画像のキャプション付けは、特定の画像のキャプションを予測するタスクです。一般的な現実世界のアプリケーションには次のものがあります。
+視覚障害者がさまざまな状況を乗り越えられるよう支援します。したがって、画像のキャプション
+画像を説明することで人々のコンテンツへのアクセシビリティを向上させるのに役立ちます。
+
+このガイドでは、次の方法を説明します。
+
+* 画像キャプション モデルを微調整します。
+* 微調整されたモデルを推論に使用します。
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install transformers datasets evaluate -q
+pip install jiwer -q
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+
+```python
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+## Load the Pokémon BLIP captions dataset
+
+🤗 データセット ライブラリを使用して、{image-caption} ペアで構成されるデータセットを読み込みます。独自の画像キャプション データセットを作成するには
+PyTorch では、[このノートブック](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/GIT/Fine_tune_GIT_on_an_image_captioning_dataset.ipynb) を参照できます。
+
+```py
+ds = load_dataset("lambdalabs/pokemon-blip-captions")
+ds
+```
+
+```bash
+DatasetDict({
+ train: Dataset({
+ features: ['image', 'text'],
+ num_rows: 833
+ })
+})
+```
+
+データセットには `image`と`text`の 2 つの機能があります。
+
+
+
+多くの画像キャプション データセットには、画像ごとに複数のキャプションが含まれています。このような場合、一般的な戦略は、トレーニング中に利用可能なキャプションの中からランダムにキャプションをサンプリングすることです。
+
+
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットのトレイン スプリットをトレイン セットとテスト セットに分割します。
+
+```python
+ds = ds["train"].train_test_split(test_size=0.1)
+train_ds = ds["train"]
+test_ds = ds["test"]
+```
+
+トレーニング セットからのいくつかのサンプルを視覚化してみましょう。
+
+```python
+from textwrap import wrap
+import matplotlib.pyplot as plt
+import numpy as np
+
+
+def plot_images(images, captions):
+ plt.figure(figsize=(20, 20))
+ for i in range(len(images)):
+ ax = plt.subplot(1, len(images), i + 1)
+ caption = captions[i]
+ caption = "\n".join(wrap(caption, 12))
+ plt.title(caption)
+ plt.imshow(images[i])
+ plt.axis("off")
+
+
+sample_images_to_visualize = [np.array(train_ds[i]["image"]) for i in range(5)]
+sample_captions = [train_ds[i]["text"] for i in range(5)]
+plot_images(sample_images_to_visualize, sample_captions)
+```
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/knowledge_distillation_for_image_classification.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/knowledge_distillation_for_image_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..1079121c6062bceb7b53e1e71625f6744c49f6eb
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/knowledge_distillation_for_image_classification.md
@@ -0,0 +1,188 @@
+
+# Knowledge Distillation for Computer Vision
+
+[[open-in-colab]]
+
+知識の蒸留は、より大規模で複雑なモデル (教師) からより小規模で単純なモデル (生徒) に知識を伝達するために使用される手法です。あるモデルから別のモデルに知識を抽出するには、特定のタスク (この場合は画像分類) でトレーニングされた事前トレーニング済み教師モデルを取得し、画像分類でトレーニングされる生徒モデルをランダムに初期化します。次に、学生モデルをトレーニングして、その出力と教師の出力の差を最小限に抑え、動作を模倣します。これは [Distilling the Knowledge in a Neural Network by Hinton et al](https://arxiv.org/abs/1503.02531) で最初に導入されました。このガイドでは、タスク固有の知識の蒸留を行います。これには [Beans データセット](https://huggingface.co/datasets/beans) を使用します。
+
+このガイドでは、[微調整された ViT モデル](https://huggingface.co/merve/vit-mobilenet-beans-224) (教師モデル) を抽出して [MobileNet](https://huggingface.co/google/mobilenet_v2_1.4_224) (学生モデル) 🤗 Transformers の [Trainer API](https://huggingface.co/docs/transformers/en/main_classes/trainer#trainer) を使用します。
+
+蒸留とプロセスの評価に必要なライブラリをインストールしましょう。
+
+```bash
+pip install transformers datasets accelerate tensorboard evaluate --upgrade
+```
+
+この例では、教師モデルとして`merve/beans-vit-224`モデルを使用しています。これは、Bean データセットに基づいて微調整された`google/vit-base-patch16-224-in21k`に基づく画像分類モデルです。このモデルをランダムに初期化された MobileNetV2 に抽出します。
+
+次に、データセットをロードします。
+
+```python
+from datasets import load_dataset
+
+dataset = load_dataset("beans")
+```
+
+この場合、同じ解像度で同じ出力が返されるため、どちらのモデルの画像プロセッサも使用できます。 `dataset`の`map()`メソッドを使用して、データセットのすべての分割に前処理を適用します。
+
+```python
+from transformers import AutoImageProcessor
+teacher_processor = AutoImageProcessor.from_pretrained("merve/beans-vit-224")
+
+def process(examples):
+ processed_inputs = teacher_processor(examples["image"])
+ return processed_inputs
+
+processed_datasets = dataset.map(process, batched=True)
+```
+
+基本的に、我々は生徒モデル(ランダムに初期化されたMobileNet)が教師モデル(微調整されたビジョン変換器)を模倣することを望む。これを実現するために、まず教師と生徒からロジット出力を得る。次に、それぞれのソフトターゲットの重要度を制御するパラメータ`temperature`で分割する。`lambda`と呼ばれるパラメータは蒸留ロスの重要度を量る。この例では、`temperature=5`、`lambda=0.5`とする。生徒と教師の間の発散を計算するために、Kullback-Leibler発散損失を使用します。2つのデータPとQが与えられたとき、KLダイバージェンスはQを使ってPを表現するためにどれだけの余分な情報が必要かを説明します。もし2つが同じであれば、QからPを説明するために必要な他の情報はないので、それらのKLダイバージェンスはゼロになります。
+
+
+```python
+from transformers import TrainingArguments, Trainer
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+
+class ImageDistilTrainer(Trainer):
+ def __init__(self, *args, teacher_model=None, **kwargs):
+ super().__init__(*args, **kwargs)
+ self.teacher = teacher_model
+ self.student = student_model
+ self.loss_function = nn.KLDivLoss(reduction="batchmean")
+ device = torch.device('cuda' if torch.cuda.is_available() else 'cpu')
+ self.teacher.to(device)
+ self.teacher.eval()
+ self.temperature = temperature
+ self.lambda_param = lambda_param
+
+ def compute_loss(self, student, inputs, return_outputs=False):
+ student_output = self.student(**inputs)
+
+ with torch.no_grad():
+ teacher_output = self.teacher(**inputs)
+
+ # Compute soft targets for teacher and student
+ soft_teacher = F.softmax(teacher_output.logits / self.temperature, dim=-1)
+ soft_student = F.log_softmax(student_output.logits / self.temperature, dim=-1)
+
+ # Compute the loss
+ distillation_loss = self.loss_function(soft_student, soft_teacher) * (self.temperature ** 2)
+
+ # Compute the true label loss
+ student_target_loss = student_output.loss
+
+ # Calculate final loss
+ loss = (1. - self.lambda_param) * student_target_loss + self.lambda_param * distillation_loss
+ return (loss, student_output) if return_outputs else loss
+```
+
+次に、Hugging Face Hub にログインして、`trainer`を通じてモデルを Hugging Face Hub にプッシュできるようにします。
+
+```python
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+教師モデルと生徒モデルである`TrainingArguments`を設定しましょう。
+
+```python
+from transformers import AutoModelForImageClassification, MobileNetV2Config, MobileNetV2ForImageClassification
+
+training_args = TrainingArguments(
+ output_dir="my-awesome-model",
+ num_train_epochs=30,
+ fp16=True,
+ logging_dir=f"{repo_name}/logs",
+ logging_strategy="epoch",
+ eval_strategy="epoch",
+ save_strategy="epoch",
+ load_best_model_at_end=True,
+ metric_for_best_model="accuracy",
+ report_to="tensorboard",
+ push_to_hub=True,
+ hub_strategy="every_save",
+ hub_model_id=repo_name,
+ )
+
+num_labels = len(processed_datasets["train"].features["labels"].names)
+
+# initialize models
+teacher_model = AutoModelForImageClassification.from_pretrained(
+ "merve/beans-vit-224",
+ num_labels=num_labels,
+ ignore_mismatched_sizes=True
+)
+
+# training MobileNetV2 from scratch
+student_config = MobileNetV2Config()
+student_config.num_labels = num_labels
+student_model = MobileNetV2ForImageClassification(student_config)
+```
+
+`compute_metrics` 関数を使用して、テスト セットでモデルを評価できます。この関数は、トレーニング プロセス中にモデルの`accuracy`と`f1`を計算するために使用されます。
+
+```python
+import evaluate
+import numpy as np
+
+accuracy = evaluate.load("accuracy")
+
+def compute_metrics(eval_pred):
+ predictions, labels = eval_pred
+ acc = accuracy.compute(references=labels, predictions=np.argmax(predictions, axis=1))
+ return {"accuracy": acc["accuracy"]}
+```
+
+定義したトレーニング引数を使用して`Trainer`を初期化しましょう。データ照合装置も初期化します。
+
+
+```python
+from transformers import DefaultDataCollator
+
+data_collator = DefaultDataCollator()
+trainer = ImageDistilTrainer(
+ student_model=student_model,
+ teacher_model=teacher_model,
+ training_args=training_args,
+ train_dataset=processed_datasets["train"],
+ eval_dataset=processed_datasets["validation"],
+ data_collator=data_collator,
+ processing_class=teacher_extractor,
+ compute_metrics=compute_metrics,
+ temperature=5,
+ lambda_param=0.5
+)
+```
+
+これでモデルをトレーニングできるようになりました。
+
+```python
+trainer.train()
+```
+
+テスト セットでモデルを評価できます。
+
+
+```python
+trainer.evaluate(processed_datasets["test"])
+```
+
+テスト セットでは、モデルの精度は 72% に達します。蒸留効率の健全性チェックを行うために、同じハイパーパラメータを使用して Bean データセットで MobileNet を最初からトレーニングし、テスト セットで 63% の精度を観察しました。読者の皆様には、さまざまな事前トレーニング済み教師モデル、学生アーキテクチャ、蒸留パラメータを試していただき、その結果を報告していただくようお勧めします。抽出されたモデルのトレーニング ログとチェックポイントは [このリポジトリ](https://huggingface.co/merve/vit-mobilenet-beans-224) にあり、最初からトレーニングされた MobileNetV2 はこの [リポジトリ](https://huggingface.co/merve/resnet-mobilenet-beans-5)。
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/language_modeling.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/language_modeling.md
new file mode 100644
index 0000000000000000000000000000000000000000..1cadc0af0ac0a559dd3b332c742dffa503b4fe64
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/language_modeling.md
@@ -0,0 +1,437 @@
+
+
+# Causal language modeling
+
+
+[[open-in-colab]]
+
+
+言語モデリングには、因果的モデリングとマスクされた言語モデリングの 2 つのタイプがあります。このガイドでは、因果関係のある言語モデリングについて説明します。
+因果言語モデルはテキスト生成によく使用されます。これらのモデルは、次のようなクリエイティブなアプリケーションに使用できます。
+独自のテキスト アドベンチャーを選択するか、Copilot や CodeParrot などのインテリジェントなコーディング アシスタントを選択します。
+
+
+
+
+因果言語モデリングは、一連のトークン内の次のトークンを予測します。モデルは、次のトークンにのみ対応できます。
+左。これは、モデルが将来のトークンを認識できないことを意味します。 GPT-2 は因果的言語モデルの一例です。
+
+このガイドでは、次の方法を説明します。
+
+1. [ELI5](https:/) の [r/askscience](https://www.reddit.com/r/askscience/) サブセットで [DistilGPT2](https://huggingface.co/distilbert/distilgpt2) を微調整します。 /huggingface.co/datasets/eli5) データセット。
+2. 微調整したモデルを推論に使用します。
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/text-generation) を確認することをお勧めします。u
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install transformers datasets evaluate
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load ELI5 dataset
+
+
+まず、ELI5 データセットの r/askscience サブセットの小さいサブセットを 🤗 データセット ライブラリからロードします。
+ これにより、完全なデータセットのトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が得られます。
+
+```py
+>>> from datasets import load_dataset
+
+>>> eli5 = load_dataset("eli5", split="train_asks[:5000]")
+```
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train_asks` をトレイン セットとテスト セットに分割します。
+
+```py
+>>> eli5 = eli5.train_test_split(test_size=0.2)
+```
+
+次に、例を見てみましょう。
+
+```py
+>>> eli5["train"][0]
+{'answers': {'a_id': ['c3d1aib', 'c3d4lya'],
+ 'score': [6, 3],
+ 'text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
+ "Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"]},
+ 'answers_urls': {'url': []},
+ 'document': '',
+ 'q_id': 'nyxfp',
+ 'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
+ 'selftext_urls': {'url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg']},
+ 'subreddit': 'askscience',
+ 'title': 'Few questions about this space walk photograph.',
+ 'title_urls': {'url': []}}
+```
+
+これは多くのことのように見えるかもしれませんが、実際に関心があるのは`text`フィールドだけです。言語モデリングの優れている点
+タスクでは、次の単語がラベル * であるため、ラベル (教師なしタスクとも呼ばれます) は必要ありません。
+
+
+## Preprocess
+
+
+
+
+次のステップは、`text`サブフィールドを処理するために DistilGPT2 トークナイザーをロードすることです。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilgpt2")
+```
+
+上の例からわかるように、`text`フィールドは実際には`answers`内にネストされています。つまり、次のことが必要になります。
+[` flatten`](https://huggingface.co/docs/datasets/process.html#flatten) メソッドを使用して、ネストされた構造から `text` サブフィールドを抽出します。
+
+```py
+>>> eli5 = eli5.flatten()
+>>> eli5["train"][0]
+{'answers.a_id': ['c3d1aib', 'c3d4lya'],
+ 'answers.score': [6, 3],
+ 'answers.text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
+ "Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"],
+ 'answers_urls.url': [],
+ 'document': '',
+ 'q_id': 'nyxfp',
+ 'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
+ 'selftext_urls.url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg'],
+ 'subreddit': 'askscience',
+ 'title': 'Few questions about this space walk photograph.',
+ 'title_urls.url': []}
+```
+
+`answers`接頭辞で示されるように、各サブフィールドは個別の列になり、`text`フィールドはリストになりました。その代わり
+各文を個別にトークン化する場合は、リストを文字列に変換して、それらをまとめてトークン化できるようにします。
+
+以下は、各例の文字列のリストを結合し、結果をトークン化する最初の前処理関数です。
+
+```py
+>>> def preprocess_function(examples):
+... return tokenizer([" ".join(x) for x in examples["answers.text"]])
+```
+
+この前処理関数をデータセット全体に適用するには、🤗 Datasets [`~datasets.Dataset.map`] メソッドを使用します。 `map` 関数を高速化するには、`batched=True` を設定してデータセットの複数の要素を一度に処理し、`num_proc` でプロセスの数を増やします。不要な列を削除します。
+
+```py
+>>> tokenized_eli5 = eli5.map(
+... preprocess_function,
+... batched=True,
+... num_proc=4,
+... remove_columns=eli5["train"].column_names,
+... )
+```
+
+このデータセットにはトークン シーケンスが含まれていますが、その一部はモデルの最大入力長よりも長くなります。
+
+2 番目の前処理関数を使用して、
+- すべてのシーケンスを連結します
+- 連結されたシーケンスを`block_size`で定義された短いチャンクに分割します。これは、最大入力長より短く、GPU RAM に十分な長さである必要があります。
+
+```py
+>>> block_size = 128
+
+
+>>> def group_texts(examples):
+... # Concatenate all texts.
+... concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
+... total_length = len(concatenated_examples[list(examples.keys())[0]])
+... # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
+... # customize this part to your needs.
+... if total_length >= block_size:
+... total_length = (total_length // block_size) * block_size
+... # Split by chunks of block_size.
+... result = {
+... k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+... for k, t in concatenated_examples.items()
+... }
+... result["labels"] = result["input_ids"].copy()
+... return result
+```
+
+Apply the `group_texts` function over the entire dataset:
+
+```py
+>>> lm_dataset = tokenized_eli5.map(group_texts, batched=True, num_proc=4)
+```
+
+次に、[`DataCollatorForLanguageModeling`] を使用してサンプルのバッチを作成します。 *動的にパディング*する方が効率的です。
+データセット全体を最大長までパディングするのではなく、照合中にバッチ内の文を最長の長さにします。
+
+
+
+
+シーケンス終了トークンをパディング トークンとして使用し、`mlm=False` を設定します。これは、入力を 1 要素分右にシフトしたラベルとして使用します。
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> tokenizer.pad_token = tokenizer.eos_token
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False)
+```
+
+
+
+シーケンス終了トークンをパディング トークンとして使用し、`mlm=False` を設定します。これは、入力を 1 要素分右にシフトしたラベルとして使用します。
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False, return_tensors="tf")
+```
+
+
+
+
+
+## Train
+
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[基本チュートリアル](../training#train-with-pytorch-trainer) を参照してください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForCausalLM`] を使用して DistilGPT2 をロードします。
+
+
+```py
+>>> from transformers import AutoModelForCausalLM, TrainingArguments, Trainer
+
+>>> model = AutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+この時点で残っている手順は次の 3 つだけです。
+
+1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。
+2. トレーニング引数をモデル、データセット、データ照合器とともに [`Trainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_eli5_clm-model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=lm_dataset["train"],
+... eval_dataset=lm_dataset["test"],
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.evaluate`] メソッドを使用してモデルを評価し、その複雑さを取得します。
+
+```py
+>>> import math
+
+>>> eval_results = trainer.evaluate()
+>>> print(f"Perplexity: {math.exp(eval_results['eval_loss']):.2f}")
+Perplexity: 49.61
+```
+
+次に、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras を使用したモデルの微調整に慣れていない場合は、[基本チュートリアル](../training#train-a-tensorflow-model-with-keras) をご覧ください。
+
+
+TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+次に、[`TFAutoModelForCausalLM`] を使用して DistilGPT2 をロードできます。
+
+```py
+>>> from transformers import TFAutoModelForCausalLM
+
+>>> model = TFAutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... lm_dataset["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... lm_dataset["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+これは、モデルとトークナイザーを [`~transformers.PushToHubCallback`] でプッシュする場所を指定することで実行できます。
+
+
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_eli5_clm-model",
+... tokenizer=tokenizer,
+... )
+```
+
+ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
+
+
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=[callback])
+```
+
+トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
+
+
+
+
+
+
+因果言語モデリング用にモデルを微調整する方法のより詳細な例については、対応するドキュメントを参照してください。
+[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)
+または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)。
+
+
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+テキストを生成するプロンプトを考え出します。
+
+```py
+>>> prompt = "Somatic hypermutation allows the immune system to"
+```
+
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用してテキスト生成用の`pipeline`をインスタンス化し、それにテキストを渡します。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline("text-generation", model="my_awesome_eli5_clm-model")
+>>> generator(prompt)
+[{'generated_text': "Somatic hypermutation allows the immune system to be able to effectively reverse the damage caused by an infection.\n\n\nThe damage caused by an infection is caused by the immune system's ability to perform its own self-correcting tasks."}]
+```
+
+
+
+
+
+テキストをトークン化し、「input_ids」を PyTorch テンソルとして返します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_clm-model")
+>>> inputs = tokenizer(prompt, return_tensors="pt").input_ids
+```
+
+[`~generation.GenerationMixin.generate`] メソッドを使用してテキストを生成します。
+さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[テキスト生成戦略](../generation_strategies) ページを参照してください。
+
+```py
+>>> from transformers import AutoModelForCausalLM
+
+>>> model = AutoModelForCausalLM.from_pretrained("my_awesome_eli5_clm-model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=True, top_k=50, top_p=0.95)
+```
+
+生成されたトークン ID をデコードしてテキストに戻します。
+
+```py
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+["Somatic hypermutation allows the immune system to react to drugs with the ability to adapt to a different environmental situation. In other words, a system of 'hypermutation' can help the immune system to adapt to a different environmental situation or in some cases even a single life. In contrast, researchers at the University of Massachusetts-Boston have found that 'hypermutation' is much stronger in mice than in humans but can be found in humans, and that it's not completely unknown to the immune system. A study on how the immune system"]
+```
+
+
+
+
+テキストをトークン化し、`input_ids`を TensorFlow テンソルとして返します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_clm-model")
+>>> inputs = tokenizer(prompt, return_tensors="tf").input_ids
+```
+
+[`~transformers.generation_tf_utils.TFGenerationMixin.generate`] メソッドを使用して要約を作成します。さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[テキスト生成戦略](../generation_strategies) ページを参照してください。
+
+```py
+>>> from transformers import TFAutoModelForCausalLM
+
+>>> model = TFAutoModelForCausalLM.from_pretrained("my_awesome_eli5_clm-model")
+>>> outputs = model.generate(input_ids=inputs, max_new_tokens=100, do_sample=True, top_k=50, top_p=0.95)
+```
+
+生成されたトークン ID をデコードしてテキストに戻します。
+
+```py
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Somatic hypermutation allows the immune system to detect the presence of other viruses as they become more prevalent. Therefore, researchers have identified a high proportion of human viruses. The proportion of virus-associated viruses in our study increases with age. Therefore, we propose a simple algorithm to detect the presence of these new viruses in our samples as a sign of improved immunity. A first study based on this algorithm, which will be published in Science on Friday, aims to show that this finding could translate into the development of a better vaccine that is more effective for']
+```
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/masked_language_modeling.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/masked_language_modeling.md
new file mode 100644
index 0000000000000000000000000000000000000000..29d7b73ae5d026f210de5c9d82401224a4a94bda
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/masked_language_modeling.md
@@ -0,0 +1,449 @@
+
+
+# Masked language modeling
+
+[[open-in-colab]]
+
+
+
+マスクされた言語モデリングはシーケンス内のマスクされたトークンを予測し、モデルはトークンを双方向に処理できます。これ
+これは、モデルが左右のトークンに完全にアクセスできることを意味します。マスクされた言語モデリングは、次のようなタスクに最適です。
+シーケンス全体の文脈をよく理解する必要があります。 BERT はマスクされた言語モデルの一例です。
+
+このガイドでは、次の方法を説明します。
+
+1. [ELI5](https://huggingface.co/distilbert/distilroberta-base) の [r/askscience](https://www.reddit.com/r/askscience/) サブセットで [DistilRoBERTa](https://huggingface.co/distilbert/distilroberta-base) を微調整します。 ://huggingface.co/datasets/eli5) データセット。
+2. 微調整したモデルを推論に使用します。
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/fill-mask) を確認することをお勧めします。
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install transformers datasets evaluate
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load ELI5 dataset
+
+まず、ELI5 データセットの r/askscience サブセットの小さいサブセットを 🤗 データセット ライブラリからロードします。これで
+データセット全体のトレーニングにさらに時間を費やす前に、実験してすべてが機能することを確認する機会が与えられます。
+
+```py
+>>> from datasets import load_dataset
+
+>>> eli5 = load_dataset("eli5", split="train_asks[:5000]")
+```
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットの `train_asks` をトレイン セットとテスト セットに分割します。
+
+```py
+>>> eli5 = eli5.train_test_split(test_size=0.2)
+```
+
+次に、例を見てみましょう。
+
+```py
+>>> eli5["train"][0]
+{'answers': {'a_id': ['c3d1aib', 'c3d4lya'],
+ 'score': [6, 3],
+ 'text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
+ "Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"]},
+ 'answers_urls': {'url': []},
+ 'document': '',
+ 'q_id': 'nyxfp',
+ 'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
+ 'selftext_urls': {'url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg']},
+ 'subreddit': 'askscience',
+ 'title': 'Few questions about this space walk photograph.',
+ 'title_urls': {'url': []}}
+```
+
+これは多くのことのように見えるかもしれませんが、実際に関心があるのは`text`フィールドだけです。言語モデリング タスクの優れた点は、次の単語がラベル * であるため、ラベル (教師なしタスクとも呼ばれます) が必要ないことです。
+
+## Preprocess
+
+
+
+マスクされた言語モデリングの場合、次のステップは、`text`サブフィールドを処理するために DistilRoBERTa トークナイザーをロードすることです。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilroberta-base")
+```
+
+上の例からわかるように、`text`フィールドは実際には`answers`内にネストされています。これは、次のことを行う必要があることを意味します
+[` flatten`](https://huggingface.co/docs/datasets/process.html#flatten) メソッドを使用して、ネストされた構造から `text` サブフィールドを抽出します。
+
+```py
+>>> eli5 = eli5.flatten()
+>>> eli5["train"][0]
+{'answers.a_id': ['c3d1aib', 'c3d4lya'],
+ 'answers.score': [6, 3],
+ 'answers.text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
+ "Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"],
+ 'answers_urls.url': [],
+ 'document': '',
+ 'q_id': 'nyxfp',
+ 'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
+ 'selftext_urls.url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg'],
+ 'subreddit': 'askscience',
+ 'title': 'Few questions about this space walk photograph.',
+ 'title_urls.url': []}
+```
+
+`answers`接頭辞で示されるように、各サブフィールドは個別の列になり、`text`フィールドはリストになりました。その代わり
+各文を個別にトークン化する場合は、リストを文字列に変換して、それらをまとめてトークン化できるようにします。
+
+以下は、各例の文字列のリストを結合し、結果をトークン化する最初の前処理関数です。
+
+```py
+>>> def preprocess_function(examples):
+... return tokenizer([" ".join(x) for x in examples["answers.text"]])
+```
+
+この前処理関数をデータセット全体に適用するには、🤗 Datasets [`~datasets.Dataset.map`] メソッドを使用します。 `map` 関数を高速化するには、`batched=True` を設定してデータセットの複数の要素を一度に処理し、`num_proc` でプロセスの数を増やします。不要な列を削除します。
+
+```py
+>>> tokenized_eli5 = eli5.map(
+... preprocess_function,
+... batched=True,
+... num_proc=4,
+... remove_columns=eli5["train"].column_names,
+... )
+```
+
+このデータセットにはトークン シーケンスが含まれていますが、その一部はモデルの最大入力長よりも長くなります。
+
+2 番目の前処理関数を使用して、
+- すべてのシーケンスを連結します
+- 連結されたシーケンスを`block_size`で定義された短いチャンクに分割します。これは、最大入力長より短く、GPU RAM に十分な長さである必要があります。
+
+```py
+>>> block_size = 128
+
+
+>>> def group_texts(examples):
+... # Concatenate all texts.
+... concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
+... total_length = len(concatenated_examples[list(examples.keys())[0]])
+... # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
+... # customize this part to your needs.
+... if total_length >= block_size:
+... total_length = (total_length // block_size) * block_size
+... # Split by chunks of block_size.
+... result = {
+... k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+... for k, t in concatenated_examples.items()
+... }
+... return result
+```
+
+データセット全体に`group_texts`関数を適用します。
+
+```py
+>>> lm_dataset = tokenized_eli5.map(group_texts, batched=True, num_proc=4)
+```
+
+次に、[`DataCollatorForLanguageModeling`] を使用してサンプルのバッチを作成します。データセット全体を最大長までパディングするのではなく、照合中にバッチ内の最長の長さまで文を *動的にパディング* する方が効率的です。
+
+
+
+
+シーケンス終了トークンをパディング トークンとして使用し、データを反復するたびにランダムにトークンをマスクするために `mlm_probability` を指定します。
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> tokenizer.pad_token = tokenizer.eos_token
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=0.15)
+```
+
+
+
+シーケンス終了トークンをパディング トークンとして使用し、データを反復するたびにランダムにトークンをマスクするために `mlm_probability` を指定します。
+
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=0.15, return_tensors="tf")
+```
+
+
+
+## Train
+
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[ここ](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForMaskedLM`] を使用して DistilRoBERTa をロードします。
+
+```py
+>>> from transformers import AutoModelForMaskedLM
+
+>>> model = AutoModelForMaskedLM.from_pretrained("distilbert/distilroberta-base")
+```
+
+この時点で残っている手順は次の 3 つだけです。
+
+1. [`TrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。
+2. トレーニング引数をモデル、データセット、データ照合器とともに [`Trainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_eli5_mlm_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=lm_dataset["train"],
+... eval_dataset=lm_dataset["test"],
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.evaluate`] メソッドを使用してモデルを評価し、その複雑さを取得します。
+
+
+```py
+>>> import math
+
+>>> eval_results = trainer.evaluate()
+>>> print(f"Perplexity: {math.exp(eval_results['eval_loss']):.2f}")
+Perplexity: 8.76
+```
+
+次に、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+Keras を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-a-tensorflow-model-with-keras) の基本的なチュートリアルをご覧ください。
+
+
+
+TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+次に、[`TFAutoModelForMaskedLM`] を使用して DistilRoBERTa をロードできます。
+
+```py
+>>> from transformers import TFAutoModelForMaskedLM
+
+>>> model = TFAutoModelForMaskedLM.from_pretrained("distilbert/distilroberta-base")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... lm_dataset["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... lm_dataset["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
+
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+This can be done by specifying where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_eli5_mlm_model",
+... tokenizer=tokenizer,
+... )
+```
+
+ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
+
+
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=[callback])
+```
+
+トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
+
+
+
+
+
+
+マスクされた言語モデリング用にモデルを微調整する方法のより詳細な例については、対応するドキュメントを参照してください。
+[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)
+または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)。
+
+
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+モデルに空白を埋めるテキストを考え出し、特別な `` トークンを使用して空白を示します。
+
+```py
+>>> text = "The Milky Way is a galaxy."
+```
+
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用してフィルマスクの`pipeline`をインスタンス化し、テキストをそれに渡します。必要に応じて、`top_k`パラメータを使用して、返す予測の数を指定できます。
+
+```py
+>>> from transformers import pipeline
+
+>>> mask_filler = pipeline("fill-mask", "stevhliu/my_awesome_eli5_mlm_model")
+>>> mask_filler(text, top_k=3)
+[{'score': 0.5150994658470154,
+ 'token': 21300,
+ 'token_str': ' spiral',
+ 'sequence': 'The Milky Way is a spiral galaxy.'},
+ {'score': 0.07087188959121704,
+ 'token': 2232,
+ 'token_str': ' massive',
+ 'sequence': 'The Milky Way is a massive galaxy.'},
+ {'score': 0.06434620916843414,
+ 'token': 650,
+ 'token_str': ' small',
+ 'sequence': 'The Milky Way is a small galaxy.'}]
+```
+
+
+
+
+テキストをトークン化し、`input_ids`を PyTorch テンソルとして返します。 `` トークンの位置も指定する必要があります。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+>>> mask_token_index = torch.where(inputs["input_ids"] == tokenizer.mask_token_id)[1]
+```
+
+入力をモデルに渡し、マスクされたトークンの`logits`を返します。
+
+```py
+>>> from transformers import AutoModelForMaskedLM
+
+>>> model = AutoModelForMaskedLM.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
+>>> logits = model(**inputs).logits
+>>> mask_token_logits = logits[0, mask_token_index, :]
+```
+
+次に、マスクされた 3 つのトークンを最も高い確率で返し、出力します。
+
+```py
+>>> top_3_tokens = torch.topk(mask_token_logits, 3, dim=1).indices[0].tolist()
+
+>>> for token in top_3_tokens:
+... print(text.replace(tokenizer.mask_token, tokenizer.decode([token])))
+The Milky Way is a spiral galaxy.
+The Milky Way is a massive galaxy.
+The Milky Way is a small galaxy.
+```
+
+
+
+
+テキストをトークン化し、`input_ids`を TensorFlow テンソルとして返します。 `` トークンの位置も指定する必要があります。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+>>> mask_token_index = tf.where(inputs["input_ids"] == tokenizer.mask_token_id)[0, 1]
+```
+
+入力をモデルに渡し、マスクされたトークンの`logits`を返します。
+
+
+```py
+>>> from transformers import TFAutoModelForMaskedLM
+
+>>> model = TFAutoModelForMaskedLM.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
+>>> logits = model(**inputs).logits
+>>> mask_token_logits = logits[0, mask_token_index, :]
+```
+
+次に、マスクされた 3 つのトークンを最も高い確率で返し、出力します。
+
+
+```py
+>>> top_3_tokens = tf.math.top_k(mask_token_logits, 3).indices.numpy()
+
+>>> for token in top_3_tokens:
+... print(text.replace(tokenizer.mask_token, tokenizer.decode([token])))
+The Milky Way is a spiral galaxy.
+The Milky Way is a massive galaxy.
+The Milky Way is a small galaxy.
+```
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/monocular_depth_estimation.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/monocular_depth_estimation.md
new file mode 100644
index 0000000000000000000000000000000000000000..e7a3a994a60ebc3ee752cfd0461bb7436c7b8406
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/monocular_depth_estimation.md
@@ -0,0 +1,149 @@
+
+
+# Monocular depth estimation
+
+単眼奥行き推定は、シーンの奥行き情報を画像から予測することを含むコンピューター ビジョン タスクです。
+単一の画像。言い換えれば、シーン内のオブジェクトの距離を距離から推定するプロセスです。
+単一カメラの視点。
+
+単眼奥行き推定には、3D 再構築、拡張現実、自動運転、
+そしてロボット工学。モデルがオブジェクト間の複雑な関係を理解する必要があるため、これは困難な作業です。
+シーンとそれに対応する深度情報(照明条件などの要因の影響を受ける可能性があります)
+オクルージョンとテクスチャ。
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/depth-estimation) を確認することをお勧めします。
+
+
+
+このガイドでは、次の方法を学びます。
+
+* 深度推定パイプラインを作成する
+* 手動で深度推定推論を実行します
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install -q transformers
+```
+
+## Depth estimation pipeline
+
+深度推定をサポートするモデルで推論を試す最も簡単な方法は、対応する [`pipeline`] を使用することです。
+[Hugging Face Hub のチェックポイント](https://huggingface.co/models?pipeline_tag=Depth-estimation&sort=downloads) からパイプラインをインスタンス化します。
+
+
+```py
+>>> from transformers import pipeline
+
+>>> checkpoint = "vinvino02/glpn-nyu"
+>>> depth_estimator = pipeline("depth-estimation", model=checkpoint)
+```
+
+次に、分析する画像を選択します。
+
+```py
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "https://unsplash.com/photos/HwBAsSbPBDU/download?ixid=MnwxMjA3fDB8MXxzZWFyY2h8MzR8fGNhciUyMGluJTIwdGhlJTIwc3RyZWV0fGVufDB8MHx8fDE2Nzg5MDEwODg&force=true&w=640"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> image
+```
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/summarization.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/summarization.md
new file mode 100644
index 0000000000000000000000000000000000000000..6784696e6c95a3bdc3abe661236ad540b3304bfc
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/summarization.md
@@ -0,0 +1,404 @@
+
+
+# Summarization
+
+[[open-in-colab]]
+
+
+
+要約により、すべての重要な情報をまとめた短いバージョンの文書または記事が作成されます。これは、翻訳と並んで、シーケンス間のタスクとして定式化できるタスクのもう 1 つの例です。要約は次のようになります。
+
+- 抽出: 文書から最も関連性の高い情報を抽出します。
+- 抽象的: 最も関連性の高い情報を捉えた新しいテキストを生成します。
+
+このガイドでは、次の方法を説明します。
+
+1. 抽象的な要約のために、[BillSum](https://huggingface.co/datasets/billsum) データセットのカリフォルニア州請求書サブセットで [T5](https://huggingface.co/google-t5/t5-small) を微調整します。
+2. 微調整したモデルを推論に使用します。
+
+
+
+このタスクと互換性のあるすべてのアーキテクチャとチェックポイントを確認するには、[タスクページ](https://huggingface.co/tasks/summarization) を確認することをお勧めします。
+
+
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+```bash
+pip install transformers datasets evaluate rouge_score
+```
+
+モデルをアップロードしてコミュニティと共有できるように、Hugging Face アカウントにログインすることをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load BillSum dataset
+
+まず、🤗 データセット ライブラリから BillSum データセットの小さいカリフォルニア州請求書サブセットを読み込みます。
+
+```py
+>>> from datasets import load_dataset
+
+>>> billsum = load_dataset("billsum", split="ca_test")
+```
+
+[`~datasets.Dataset.train_test_split`] メソッドを使用して、データセットをトレイン セットとテスト セットに分割します。
+
+```py
+>>> billsum = billsum.train_test_split(test_size=0.2)
+```
+
+次に、例を見てみましょう。
+
+```py
+>>> billsum["train"][0]
+{'summary': 'Existing law authorizes state agencies to enter into contracts for the acquisition of goods or services upon approval by the Department of General Services. Existing law sets forth various requirements and prohibitions for those contracts, including, but not limited to, a prohibition on entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between spouses and domestic partners or same-sex and different-sex couples in the provision of benefits. Existing law provides that a contract entered into in violation of those requirements and prohibitions is void and authorizes the state or any person acting on behalf of the state to bring a civil action seeking a determination that a contract is in violation and therefore void. Under existing law, a willful violation of those requirements and prohibitions is a misdemeanor.\nThis bill would also prohibit a state agency from entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between employees on the basis of gender identity in the provision of benefits, as specified. By expanding the scope of a crime, this bill would impose a state-mandated local program.\nThe California Constitution requires the state to reimburse local agencies and school districts for certain costs mandated by the state. Statutory provisions establish procedures for making that reimbursement.\nThis bill would provide that no reimbursement is required by this act for a specified reason.',
+ 'text': 'The people of the State of California do enact as follows:\n\n\nSECTION 1.\nSection 10295.35 is added to the Public Contract Code, to read:\n10295.35.\n(a) (1) Notwithstanding any other law, a state agency shall not enter into any contract for the acquisition of goods or services in the amount of one hundred thousand dollars ($100,000) or more with a contractor that, in the provision of benefits, discriminates between employees on the basis of an employee’s or dependent’s actual or perceived gender identity, including, but not limited to, the employee’s or dependent’s identification as transgender.\n(2) For purposes of this section, “contract” includes contracts with a cumulative amount of one hundred thousand dollars ($100,000) or more per contractor in each fiscal year.\n(3) For purposes of this section, an employee health plan is discriminatory if the plan is not consistent with Section 1365.5 of the Health and Safety Code and Section 10140 of the Insurance Code.\n(4) The requirements of this section shall apply only to those portions of a contractor’s operations that occur under any of the following conditions:\n(A) Within the state.\n(B) On real property outside the state if the property is owned by the state or if the state has a right to occupy the property, and if the contractor’s presence at that location is connected to a contract with the state.\n(C) Elsewhere in the United States where work related to a state contract is being performed.\n(b) Contractors shall treat as confidential, to the maximum extent allowed by law or by the requirement of the contractor’s insurance provider, any request by an employee or applicant for employment benefits or any documentation of eligibility for benefits submitted by an employee or applicant for employment.\n(c) After taking all reasonable measures to find a contractor that complies with this section, as determined by the state agency, the requirements of this section may be waived under any of the following circumstances:\n(1) There is only one prospective contractor willing to enter into a specific contract with the state agency.\n(2) The contract is necessary to respond to an emergency, as determined by the state agency, that endangers the public health, welfare, or safety, or the contract is necessary for the provision of essential services, and no entity that complies with the requirements of this section capable of responding to the emergency is immediately available.\n(3) The requirements of this section violate, or are inconsistent with, the terms or conditions of a grant, subvention, or agreement, if the agency has made a good faith attempt to change the terms or conditions of any grant, subvention, or agreement to authorize application of this section.\n(4) The contractor is providing wholesale or bulk water, power, or natural gas, the conveyance or transmission of the same, or ancillary services, as required for ensuring reliable services in accordance with good utility practice, if the purchase of the same cannot practically be accomplished through the standard competitive bidding procedures and the contractor is not providing direct retail services to end users.\n(d) (1) A contractor shall not be deemed to discriminate in the provision of benefits if the contractor, in providing the benefits, pays the actual costs incurred in obtaining the benefit.\n(2) If a contractor is unable to provide a certain benefit, despite taking reasonable measures to do so, the contractor shall not be deemed to discriminate in the provision of benefits.\n(e) (1) Every contract subject to this chapter shall contain a statement by which the contractor certifies that the contractor is in compliance with this section.\n(2) The department or other contracting agency shall enforce this section pursuant to its existing enforcement powers.\n(3) (A) If a contractor falsely certifies that it is in compliance with this section, the contract with that contractor shall be subject to Article 9 (commencing with Section 10420), unless, within a time period specified by the department or other contracting agency, the contractor provides to the department or agency proof that it has complied, or is in the process of complying, with this section.\n(B) The application of the remedies or penalties contained in Article 9 (commencing with Section 10420) to a contract subject to this chapter shall not preclude the application of any existing remedies otherwise available to the department or other contracting agency under its existing enforcement powers.\n(f) Nothing in this section is intended to regulate the contracting practices of any local jurisdiction.\n(g) This section shall be construed so as not to conflict with applicable federal laws, rules, or regulations. In the event that a court or agency of competent jurisdiction holds that federal law, rule, or regulation invalidates any clause, sentence, paragraph, or section of this code or the application thereof to any person or circumstances, it is the intent of the state that the court or agency sever that clause, sentence, paragraph, or section so that the remainder of this section shall remain in effect.\nSEC. 2.\nSection 10295.35 of the Public Contract Code shall not be construed to create any new enforcement authority or responsibility in the Department of General Services or any other contracting agency.\nSEC. 3.\nNo reimbursement is required by this act pursuant to Section 6 of Article XIII\u2009B of the California Constitution because the only costs that may be incurred by a local agency or school district will be incurred because this act creates a new crime or infraction, eliminates a crime or infraction, or changes the penalty for a crime or infraction, within the meaning of Section 17556 of the Government Code, or changes the definition of a crime within the meaning of Section 6 of Article XIII\u2009B of the California Constitution.',
+ 'title': 'An act to add Section 10295.35 to the Public Contract Code, relating to public contracts.'}
+```
+
+使用するフィールドが 2 つあります。
+
+- `text`: モデルへの入力となる請求書のテキスト。
+- `summary`: モデルのターゲットとなる `text` の要約版。
+
+## Preprocess
+
+次のステップでは、T5 トークナイザーをロードして「text」と`summary`を処理します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> checkpoint = "google-t5/t5-small"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+```
+
+作成する前処理関数は次のことを行う必要があります。
+
+1. T5 がこれが要約タスクであることを認識できるように、入力の前にプロンプトを付けます。複数の NLP タスクが可能な一部のモデルでは、特定のタスクのプロンプトが必要です。
+2. ラベルをトークン化するときにキーワード `text_target` 引数を使用します。
+3. `max_length`パラメータで設定された最大長を超えないようにシーケンスを切り詰めます。
+
+```py
+>>> prefix = "summarize: "
+
+
+>>> def preprocess_function(examples):
+... inputs = [prefix + doc for doc in examples["text"]]
+... model_inputs = tokenizer(inputs, max_length=1024, truncation=True)
+
+... labels = tokenizer(text_target=examples["summary"], max_length=128, truncation=True)
+
+... model_inputs["labels"] = labels["input_ids"]
+... return model_inputs
+```
+
+データセット全体に前処理関数を適用するには、🤗 Datasets [`~datasets.Dataset.map`] メソッドを使用します。 `batched=True` を設定してデータセットの複数の要素を一度に処理することで、`map` 関数を高速化できます。
+
+```py
+>>> tokenized_billsum = billsum.map(preprocess_function, batched=True)
+```
+
+次に、[`DataCollatorForSeq2Seq`] を使用してサンプルのバッチを作成します。データセット全体を最大長までパディングするのではなく、照合中にバッチ内の最長の長さまで文を *動的にパディング* する方が効率的です。
+
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint)
+```
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint, return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+トレーニング中にメトリクスを含めると、多くの場合、モデルのパフォーマンスを評価するのに役立ちます。 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) ライブラリを使用して、評価メソッドをすばやくロードできます。このタスクでは、[ROUGE](https://huggingface.co/spaces/evaluate-metric/rouge) メトリックを読み込みます (🤗 Evaluate [クイック ツアー](https://huggingface.co/docs/evaluate/a_quick_tour) を参照してください) ) メトリクスをロードして計算する方法の詳細については、次を参照してください)。
+
+```py
+>>> import evaluate
+
+>>> rouge = evaluate.load("rouge")
+```
+
+次に、予測とラベルを [`~evaluate.EvaluationModule.compute`] に渡して ROUGE メトリクスを計算する関数を作成します。
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... decoded_preds = tokenizer.batch_decode(predictions, skip_special_tokens=True)
+... labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+... decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+... result = rouge.compute(predictions=decoded_preds, references=decoded_labels, use_stemmer=True)
+
+... prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in predictions]
+... result["gen_len"] = np.mean(prediction_lens)
+
+... return {k: round(v, 4) for k, v in result.items()}
+```
+
+これで`compute_metrics`関数の準備が整いました。トレーニングをセットアップするときにこの関数に戻ります。
+
+## Train
+
+
+
+
+
+
+[`Trainer`] を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-with-pytorch-trainer) の基本的なチュートリアルをご覧ください。
+
+
+
+これでモデルのトレーニングを開始する準備が整いました。 [`AutoModelForSeq2SeqLM`] を使用して T5 をロードします。
+
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM, Seq2SeqTrainingArguments, Seq2SeqTrainer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+この時点で残っている手順は次の 3 つだけです。
+
+1. [`Seq2SeqTrainingArguments`] でトレーニング ハイパーパラメータを定義します。唯一の必須パラメータは、モデルの保存場所を指定する `output_dir` です。 `push_to_hub=True`を設定して、このモデルをハブにプッシュします (モデルをアップロードするには、Hugging Face にサインインする必要があります)。各エポックの終了時に、[`Trainer`] は ROUGE メトリクスを評価し、トレーニング チェックポイントを保存します。
+2. トレーニング引数をモデル、データセット、トークナイザー、データ照合器、および `compute_metrics` 関数とともに [`Seq2SeqTrainer`] に渡します。
+3. [`~Trainer.train`] を呼び出してモデルを微調整します。
+
+```py
+>>> training_args = Seq2SeqTrainingArguments(
+... output_dir="my_awesome_billsum_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... weight_decay=0.01,
+... save_total_limit=3,
+... num_train_epochs=4,
+... predict_with_generate=True,
+... fp16=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Seq2SeqTrainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_billsum["train"],
+... eval_dataset=tokenized_billsum["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+トレーニングが完了したら、 [`~transformers.Trainer.push_to_hub`] メソッドを使用してモデルをハブに共有し、誰もがモデルを使用できるようにします。
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras を使用したモデルの微調整に慣れていない場合は、[こちら](../training#train-a-tensorflow-model-with-keras) の基本的なチュートリアルをご覧ください。
+
+
+TensorFlow でモデルを微調整するには、オプティマイザー関数、学習率スケジュール、およびいくつかのトレーニング ハイパーパラメーターをセットアップすることから始めます。
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+次に、[`TFAutoModelForSeq2SeqLM`] を使用して T5 をロードできます。
+
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] を使用して、データセットを `tf.data.Dataset` 形式に変換します。
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_billsum["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... tokenized_billsum["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) を使用してトレーニング用のモデルを設定します。 Transformers モデルにはすべてデフォルトのタスク関連の損失関数があるため、次の場合を除き、損失関数を指定する必要はないことに注意してください。
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+トレーニングを開始する前にセットアップする最後の 2 つのことは、予測から ROUGE スコアを計算し、モデルをハブにプッシュする方法を提供することです。どちらも [Keras コールバック](../main_classes/keras_callbacks) を使用して行われます。
+
+`compute_metrics` 関数を [`~transformers.KerasMetricCallback`] に渡します。
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+Specify where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_billsum_model",
+... tokenizer=tokenizer,
+... )
+```
+
+次に、コールバックをまとめてバンドルします。
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+ついに、モデルのトレーニングを開始する準備が整いました。トレーニングおよび検証データセット、エポック数、コールバックを指定して [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) を呼び出し、モデルを微調整します。
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=callbacks)
+```
+
+トレーニングが完了すると、モデルは自動的にハブにアップロードされ、誰でも使用できるようになります。
+
+
+
+
+
+
+要約用にモデルを微調整する方法のより詳細な例については、対応するセクションを参照してください。
+[PyTorch ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization.ipynb)
+または [TensorFlow ノートブック](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization-tf.ipynb)。
+
+
+
+## Inference
+
+モデルを微調整したので、それを推論に使用できるようになりました。
+
+要約したいテキストを考え出します。 T5 の場合、作業中のタスクに応じて入力に接頭辞を付ける必要があります。要約するには、以下に示すように入力にプレフィックスを付ける必要があります。
+
+```py
+>>> text = "summarize: The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country. It'll lower the deficit and ask the ultra-wealthy and corporations to pay their fair share. And no one making under $400,000 per year will pay a penny more in taxes."
+```
+
+推論用に微調整されたモデルを試す最も簡単な方法は、それを [`pipeline`] で使用することです。モデルを使用して要約用の `pipeline` をインスタンス化し、テキストをそれに渡します。
+
+```py
+>>> from transformers import pipeline
+
+>>> summarizer = pipeline("summarization", model="stevhliu/my_awesome_billsum_model")
+>>> summarizer(text)
+[{"summary_text": "The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country."}]
+```
+
+必要に応じて、`pipeline`」の結果を手動で複製することもできます。
+
+
+
+Tokenize the text and return the `input_ids` as PyTorch tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> inputs = tokenizer(text, return_tensors="pt").input_ids
+```
+
+[`~generation.GenerationMixin.generate`] メソッドを使用して要約を作成します。さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[Text Generation](../main_classes/text_generation) API を確認してください。
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
+```
+
+生成されたトークン ID をデコードしてテキストに戻します。
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
+```
+
+
+
+テキストをトークン化し、`input_ids`を TensorFlow テンソルとして返します。
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> inputs = tokenizer(text, return_tensors="tf").input_ids
+```
+
+[`~transformers.generation_tf_utils.TFGenerationMixin.generate`] メソッドを使用して要約を作成します。さまざまなテキスト生成戦略と生成を制御するためのパラメーターの詳細については、[Text Generation](../main_classes/text_generation) API を確認してください。
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
+```
+
+生成されたトークン ID をデコードしてテキストに戻します。
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
+```
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/text-to-speech.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/text-to-speech.md
new file mode 100644
index 0000000000000000000000000000000000000000..669d15730e24f892e27103a9ad48733b5e7fb34d
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tasks/text-to-speech.md
@@ -0,0 +1,638 @@
+
+
+# Text to speech
+
+[[open-in-colab]]
+
+テキスト読み上げ (TTS) は、テキストから自然な音声を作成するタスクです。音声は複数の形式で生成できます。
+言語と複数の話者向け。現在、いくつかのテキスト読み上げモデルが 🤗 Transformers で利用可能です。
+[Bark](../model_doc/bark)、[MMS](../model_doc/mms)、[VITS](../model_doc/vits)、および [SpeechT5](../model_doc/speecht5)。
+
+`text-to-audio`パイプライン (またはその別名 - `text-to-speech`) を使用して、音声を簡単に生成できます。 Bark などの一部のモデルは、
+笑い、ため息、泣きなどの非言語コミュニケーションを生成したり、音楽を追加したりするように条件付けすることもできます。
+Bark で`text-to-speech`パイプラインを使用する方法の例を次に示します。
+
+```py
+>>> from transformers import pipeline
+
+>>> pipe = pipeline("text-to-speech", model="suno/bark-small")
+>>> text = "[clears throat] This is a test ... and I just took a long pause."
+>>> output = pipe(text)
+```
+
+ノートブックで結果の音声を聞くために使用できるコード スニペットを次に示します。
+
+```python
+>>> from IPython.display import Audio
+>>> Audio(output["audio"], rate=output["sampling_rate"])
+```
+Bark およびその他の事前トレーニングされた TTS モデルができることの詳細な例については、次のドキュメントを参照してください。
+[音声コース](https://huggingface.co/learn/audio-course/chapter6/pre-trained_models)。
+
+TTS モデルを微調整する場合、現在微調整できるのは SpeechT5 のみです。 SpeechT5 は、次の組み合わせで事前トレーニングされています。
+音声からテキストへのデータとテキストから音声へのデータ。両方のテキストに共有される隠された表現の統一された空間を学習できるようにします。
+そしてスピーチ。これは、同じ事前トレーニング済みモデルをさまざまなタスクに合わせて微調整できることを意味します。さらに、SpeechT5
+X ベクトル スピーカーの埋め込みを通じて複数のスピーカーをサポートします。
+
+このガイドの残りの部分では、次の方法を説明します。
+
+1. [VoxPopuli](https://huggingface.co/datasets/facebook/voxpopuli) のオランダ語 (`nl`) 言語サブセット上の英語音声で元々トレーニングされた [SpeechT5](../model_doc/speecht5) を微調整します。 データセット。
+2. パイプラインを使用するか直接使用するかの 2 つの方法のいずれかで、洗練されたモデルを推論に使用します。
+
+始める前に、必要なライブラリがすべてインストールされていることを確認してください。
+
+
+```bash
+pip install datasets soundfile speechbrain accelerate
+```
+
+SpeechT5 のすべての機能がまだ正式リリースにマージされていないため、ソースから 🤗Transformers をインストールします。
+
+```bash
+pip install git+https://github.com/huggingface/transformers.git
+```
+
+
+
+このガイドに従うには、GPU が必要です。ノートブックで作業している場合は、次の行を実行して GPU が利用可能かどうかを確認します。
+
+```bash
+!nvidia-smi
+```
+
+
+
+Hugging Face アカウントにログインして、モデルをアップロードしてコミュニティと共有することをお勧めします。プロンプトが表示されたら、トークンを入力してログインします。
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load the dataset
+
+[VoxPopuli](https://huggingface.co/datasets/facebook/voxpopuli) は、以下で構成される大規模な多言語音声コーパスです。
+データは 2009 年から 2020 年の欧州議会のイベント記録をソースとしています。 15 件分のラベル付き音声文字起こしデータが含まれています。
+ヨーロッパの言語。このガイドではオランダ語のサブセットを使用していますが、自由に別のサブセットを選択してください。
+
+VoxPopuli またはその他の自動音声認識 (ASR) データセットは最適ではない可能性があることに注意してください。
+TTS モデルをトレーニングするためのオプション。過剰なバックグラウンドノイズなど、ASR にとって有益となる機能は次のとおりです。
+通常、TTS では望ましくありません。ただし、最高品質、多言語、マルチスピーカーの TTS データセットを見つけるのは非常に困難な場合があります。
+挑戦的。
+
+データをロードしましょう:
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("facebook/voxpopuli", "nl", split="train")
+>>> len(dataset)
+20968
+```
+
+微調整には 20968 個の例で十分です。 SpeechT5 はオーディオ データのサンプリング レートが 16 kHz であることを想定しているため、
+データセット内の例がこの要件を満たしていることを確認してください。
+
+
+```py
+dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+```
+
+## Preprocess the data
+
+使用するモデル チェックポイントを定義し、適切なプロセッサをロードすることから始めましょう。
+
+
+```py
+>>> from transformers import SpeechT5Processor
+
+>>> checkpoint = "microsoft/speecht5_tts"
+>>> processor = SpeechT5Processor.from_pretrained(checkpoint)
+```
+
+### Text cleanup for SpeechT5 tokenization
+
+
+まずはテキストデータをクリーンアップすることから始めます。テキストを処理するには、プロセッサのトークナイザー部分が必要です。
+
+```py
+>>> tokenizer = processor.tokenizer
+```
+
+データセットの例には、`raw_text`機能と `normalized_text`機能が含まれています。テキスト入力としてどの機能を使用するかを決めるときは、
+SpeechT5 トークナイザーには数値のトークンがないことを考慮してください。 `normalized_text`には数字が書かれています
+テキストとして出力します。したがって、これはより適切であり、入力テキストとして `normalized_text` を使用することをお勧めします。
+
+SpeechT5 は英語でトレーニングされているため、オランダ語のデータセット内の特定の文字を認識しない可能性があります。もし
+残っているように、これらの文字は ``トークンに変換されます。ただし、オランダ語では、`à`などの特定の文字は
+音節を強調することに慣れています。テキストの意味を保持するために、この文字を通常の`a`に置き換えることができます。
+
+サポートされていないトークンを識別するには、`SpeechT5Tokenizer`を使用してデータセット内のすべての一意の文字を抽出します。
+文字をトークンとして扱います。これを行うには、以下を連結する `extract_all_chars` マッピング関数を作成します。
+すべての例からの転写を 1 つの文字列にまとめ、それを文字セットに変換します。
+すべての文字起こしが一度に利用できるように、`dataset.map()`で`batched=True`と`batch_size=-1`を必ず設定してください。
+マッピング機能。
+
+```py
+>>> def extract_all_chars(batch):
+... all_text = " ".join(batch["normalized_text"])
+... vocab = list(set(all_text))
+... return {"vocab": [vocab], "all_text": [all_text]}
+
+
+>>> vocabs = dataset.map(
+... extract_all_chars,
+... batched=True,
+... batch_size=-1,
+... keep_in_memory=True,
+... remove_columns=dataset.column_names,
+... )
+
+>>> dataset_vocab = set(vocabs["vocab"][0])
+>>> tokenizer_vocab = {k for k, _ in tokenizer.get_vocab().items()}
+```
+
+これで、2 つの文字セットができました。1 つはデータセットの語彙を持ち、もう 1 つはトークナイザーの語彙を持ちます。
+データセット内でサポートされていない文字を特定するには、これら 2 つのセットの差分を取ることができます。結果として
+set には、データセットにはあるがトークナイザーには含まれていない文字が含まれます。
+
+```py
+>>> dataset_vocab - tokenizer_vocab
+{' ', 'à', 'ç', 'è', 'ë', 'í', 'ï', 'ö', 'ü'}
+```
+
+前の手順で特定されたサポートされていない文字を処理するには、これらの文字を
+有効なトークン。スペースはトークナイザーですでに `▁` に置き換えられているため、個別に処理する必要がないことに注意してください。
+
+```py
+>>> replacements = [
+... ("à", "a"),
+... ("ç", "c"),
+... ("è", "e"),
+... ("ë", "e"),
+... ("í", "i"),
+... ("ï", "i"),
+... ("ö", "o"),
+... ("ü", "u"),
+... ]
+
+
+>>> def cleanup_text(inputs):
+... for src, dst in replacements:
+... inputs["normalized_text"] = inputs["normalized_text"].replace(src, dst)
+... return inputs
+
+
+>>> dataset = dataset.map(cleanup_text)
+```
+
+テキスト内の特殊文字を扱ったので、今度は音声データに焦点を移します。
+
+### Speakers
+
+VoxPopuli データセットには複数の話者の音声が含まれていますが、データセットには何人の話者が含まれているのでしょうか?に
+これを決定すると、一意の話者の数と、各話者がデータセットに寄与する例の数を数えることができます。
+データセットには合計 20,968 個の例が含まれており、この情報により、分布をより深く理解できるようになります。
+講演者とデータ内の例。
+
+```py
+>>> from collections import defaultdict
+
+>>> speaker_counts = defaultdict(int)
+
+>>> for speaker_id in dataset["speaker_id"]:
+... speaker_counts[speaker_id] += 1
+```
+
+ヒストグラムをプロットすると、各話者にどれだけのデータがあるかを把握できます。
+
+```py
+>>> import matplotlib.pyplot as plt
+
+>>> plt.figure()
+>>> plt.hist(speaker_counts.values(), bins=20)
+>>> plt.ylabel("Speakers")
+>>> plt.xlabel("Examples")
+>>> plt.show()
+```
+
+
+
+1. BARTのエンコーダーアーキテクチャは、BERTと非常に似ており、テキストのトークンと位置エンベディングを受け入れます。BARTは、入力を破壊してからデコーダーで再構築することによって事前トレーニングされます。特定の破壊戦略を持つ他のエンコーダーとは異なり、BARTは任意の種類の破壊を適用できます。ただし、*テキストインフィリング*破壊戦略が最適です。テキストインフィリングでは、いくつかのテキストスパンが**単一の** [`mask`] トークンで置き換えられます。これは重要です、なぜならモデルはマスクされたトークンを予測しなければならず、モデルに欠落トークンの数を予測させるからです。入力埋め込みとマスクされたスパンはエンコーダーを介して最終的な隠れた状態を出力しますが、BERTとは異なり、BARTは単語を予測するための最終的なフィードフォワードネットワークを最後に追加しません。
+
+2. エンコーダーの出力はデコーダーに渡され、デコーダーはエンコーダーの出力からマスクされたトークンと非破壊トークンを予測する必要があります。これにより、デコーダーは元のテキストを復元するのに役立つ追加のコンテキストが提供されます。デコーダーからの出力は言語モデリングヘッドに渡され、隠れた状態をロジットに変換するための線形変換を実行します。クロスエントロピー損失は、ロジットとラベルの間で計算され、ラベルは単に右にシフトされたトークンです。
+
+要約を試す準備はできましたか?T5を微調整して推論に使用する方法を学ぶために、完全な[要約ガイド](tasks/summarization)をご覧ください!
+
+
+
+テキスト生成に関する詳細は、[テキスト生成戦略](generation_strategies)ガイドをチェックしてみてください!
+
+
+
+### Translation
+
+翻訳は、もう一つのシーケンス・トゥ・シーケンス・タスクの例であり、[BART](model_doc/bart) や [T5](model_doc/t5) のようなエンコーダーデコーダーモデルを使用して実行できます。このセクションでは、BARTの動作方法を説明し、最後にT5の微調整を試すことができます。
+
+BARTは、ソース言語をターゲット言語にデコードできるようにするために、別個にランダムに初期化されたエンコーダーを追加することで翻訳に適応します。この新しいエンコーダーの埋め込みは、元の単語埋め込みの代わりに事前トレーニング済みのエンコーダーに渡されます。ソースエンコーダーは、モデルの出力からのクロスエントロピー損失を用いてソースエンコーダー、位置エンベディング、および入力エンベディングを更新することによって訓練されます。この最初のステップではモデルパラメータが固定され、すべてのモデルパラメータが2番目のステップで一緒に訓練されます。
+
+その後、翻訳のために多言語版のmBARTが登場し、多言語で事前トレーニングされたモデルとして利用可能です。
+
+翻訳を試す準備はできましたか?T5を微調整して推論に使用する方法を学ぶために、完全な[翻訳ガイド](tasks/summarization)をご覧ください!
+
+
+
+テキスト生成に関する詳細は、[テキスト生成戦略](generation_strategies)ガイドをチェックしてみてください!
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/testing.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/testing.md
new file mode 100644
index 0000000000000000000000000000000000000000..8831d48a3bdaff4739b8425828d15fffbdce2b6a
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/testing.md
@@ -0,0 +1,1213 @@
+
+
+# Testing
+
+🤗 Transformersモデルがどのようにテストされ、新しいテストを書いて既存のテストを改善できるかを見てみましょう。
+
+このリポジトリには2つのテストスイートがあります:
+
+1. `tests` -- 一般的なAPI用のテスト
+2. `examples` -- APIの一部ではないさまざまなアプリケーション用のテスト
+
+## How transformers are tested
+
+1. PRが提出されると、9つのCircleCiジョブでテストされます。PRへの新しいコミットごとに再テストされます。これらのジョブは、[この設定ファイル](https://github.com/huggingface/transformers/tree/main/.circleci/config.yml)で定義されており、必要な場合は同じ環境を自分のマシンで再現できます。
+
+ これらのCIジョブは `@slow` テストを実行しません。
+
+2. [GitHub Actions](https://github.com/huggingface/transformers/actions)によって実行される3つのジョブがあります:
+
+ - [torch hub integration](https://github.com/huggingface/transformers/tree/main/.github/workflows/github-torch-hub.yml): torch hubの統合が動作するかどうかを確認します。
+
+ - [self-hosted (push)](https://github.com/huggingface/transformers/tree/main/.github/workflows/self-push.yml): `main` にコミットが行われた場合に、GPUで高速テストを実行します。このジョブは、`main` でのコミットが以下のフォルダーのコードを更新した場合にのみ実行されます:`src`、`tests`、`.github`(追加されたモデルカード、ノートブックなどの実行を防ぐため)。
+
+ - [self-hosted runner](https://github.com/huggingface/transformers/tree/main/.github/workflows/self-scheduled.yml): GPUで `tests` と `examples` の通常のテストと遅いテストを実行します。
+
+```bash
+RUN_SLOW=1 pytest tests/
+RUN_SLOW=1 pytest examples/
+```
+ 結果は[here](https://github.com/huggingface/transformers/actions)で観察できます。
+
+## Running tests
+
+
+
+### Choosing which tests to run
+
+このドキュメントは、テストを実行する方法の多くの詳細について説明しています。すべてを読んだ後でも、さらに詳細が必要な場合は、[こちら](https://docs.pytest.org/en/latest/usage.html)で見つけることができます。
+
+以下は、テストを実行するためのいくつかの最も便利な方法です。
+
+すべて実行します:
+```console
+pytest
+```
+
+または:
+```bash
+make test
+```
+
+
+後者は次のように定義されることに注意してください。
+
+```bash
+python -m pytest -n auto --dist=loadfile -s -v ./tests/
+```
+
+以下は、pytestに渡す設定情報です。
+
+- テストプロセスをCPUコアの数と同じだけ実行するように指示します。ただし、RAMが十分でない場合は注意が必要です。
+- 同じファイルからのすべてのテストは、同じテストプロセスで実行されるようにします。
+- 出力のキャプチャを行いません。
+- 冗長モードで実行します。
+
+
+### Getting the list of all tests
+
+テストスイートのすべてのテスト:
+
+```bash
+pytest --collect-only -q
+```
+
+指定されたテスト ファイルのすべてのテスト:
+
+```bash
+pytest tests/test_optimization.py --collect-only -q
+```
+
+### Run a specific test module
+
+個別のテスト モジュールを実行するには:
+
+```bash
+pytest tests/utils/test_logging.py
+```
+
+### Run specific tests
+
+ほとんどのテストでunittestが使用されているため、特定のサブテストを実行するには、それらのテストを含むunittestクラスの名前を知っている必要があります。例えば、それは次のようになるかもしれません:
+
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest::test_adam_w
+```
+
+テストの実行方法:
+
+テストファイル: `tests/test_optimization.py`
+クラス名: `OptimizationTest`
+テスト関数の名前: `test_adam_w`
+
+ファイルに複数のクラスが含まれている場合は、特定のクラスのテストのみを実行することを選択できます。例えば:
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest
+```
+
+テストクラス内のすべてのテストを実行します。
+
+前述の通り、`OptimizationTest` クラスに含まれるテストを実行するには、次のコマンドを実行できます:
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest --collect-only -q
+```
+
+キーワード式を使用してテストを実行できます。
+
+名前に `adam` が含まれるテストのみを実行するには:
+
+```bash
+pytest -k adam tests/test_optimization.py
+```
+
+`and`および`or`は、すべてのキーワードが一致するか、いずれかを示すために使用できます。`not`は否定するために使用できます。
+
+`adam`という名前を含むテストを除いてすべてのテストを実行するには:
+
+```bash
+pytest -k "not adam" tests/test_optimization.py
+```
+
+
+以下は、提供されたテキストの日本語訳です。
+
+```bash
+pytest -k "ada and not adam" tests/test_optimization.py
+```
+
+たとえば、`test_adafactor`と`test_adam_w`の両方を実行するには、以下のコマンドを使用できます:
+
+```bash
+pytest -k "test_adam_w or test_adam_w" tests/test_optimization.py
+```
+
+注意: ここでは、`or` を使用しています。キーワードのいずれか一つが一致すれば、両方を含めるためです。
+
+両方のパターンを含むテストのみを含めたい場合は、`and` を使用してください。
+
+```bash
+pytest -k "test and ada" tests/test_optimization.py
+```
+
+### Run `accelerate` tests
+
+時々、モデルに対して `accelerate` テストを実行する必要があります。たとえば、`OPT` 実行に対してこれらのテストを実行したい場合、コマンドに `-m accelerate_tests` を追加するだけで済みます:
+
+```bash
+RUN_SLOW=1 pytest -m accelerate_tests tests/models/opt/test_modeling_opt.py
+```
+
+### Run documentation tests
+
+ドキュメンテーションの例が正しいかどうかをテストするには、`doctests` が合格しているかを確認する必要があります。
+例として、[`WhisperModel.forward` のドックストリング](https://github.com/huggingface/transformers/blob/main/src/transformers/models/whisper/modeling_whisper.py#L1017-L1035)を使用しましょう。
+
+
+```python
+r"""
+Returns:
+
+Example:
+ ```python
+ >>> import torch
+ >>> from transformers import WhisperModel, WhisperFeatureExtractor
+ >>> from datasets import load_dataset
+
+ >>> model = WhisperModel.from_pretrained("openai/whisper-base")
+ >>> feature_extractor = WhisperFeatureExtractor.from_pretrained("openai/whisper-base")
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> inputs = feature_extractor(ds[0]["audio"]["array"], return_tensors="pt")
+ >>> input_features = inputs.input_features
+ >>> decoder_input_ids = torch.tensor([[1, 1]]) * model.config.decoder_start_token_id
+ >>> last_hidden_state = model(input_features, decoder_input_ids=decoder_input_ids).last_hidden_state
+ >>> list(last_hidden_state.shape)
+ [1, 2, 512]
+ ```"""
+
+```
+
+指定したファイル内のすべてのドックストリング例を自動的にテストするために、以下の行を実行してください:
+
+```bash
+pytest --doctest-modules
+```
+
+ファイルにマークダウン拡張子がある場合は、`--doctest-glob="*.md"`引数を追加する必要があります。
+
+
+### Run only modified tests
+
+[pytest-picked](https://github.com/anapaulagomes/pytest-picked)を使用すると、未ステージングのファイルまたは現在のブランチ(Gitに従って)に関連するテストを実行できます。これは、変更内容に関連するテストのみ実行されるため、変更が何も壊れていないことを迅速に確認する素晴らしい方法です。変更されていないファイルに関連するテストは実行されません。
+
+```bash
+pip install pytest-picked
+```
+
+```bash
+pytest --picked
+```
+
+すべてのテストは、変更されたがまだコミットされていないファイルとフォルダから実行されます。
+
+### Automatically rerun failed tests on source modification
+
+[pytest-xdist](https://github.com/pytest-dev/pytest-xdist)は、非常に便利な機能を提供しており、すべての失敗したテストを検出し、ファイルを修正する間にそれらの失敗したテストを連続して再実行することができます。そのため、修正を行った後にpytestを再起動する必要がありません。すべてのテストが合格するまで繰り返され、その後再度フルランが実行されます。
+
+
+```bash
+pip install pytest-xdist
+```
+
+モードに入るには: `pytest -f`または`pytest --looponfail`
+
+ファイルの変更は、`looponfailroots`ルートディレクトリとその内容全体(再帰的に)を見て検出されます。この値のデフォルトが機能しない場合、`setup.cfg`で設定オプションを変更してプロジェクト内で変更できます。
+
+
+```ini
+[tool:pytest]
+looponfailroots = transformers tests
+```
+
+または `pytest.ini`/`tox.ini` ファイル:
+
+```ini
+[pytest]
+looponfailroots = transformers tests
+```
+
+ファイルの変更を探すことは、iniファイルのディレクトリを基準にして指定されたディレクトリ内でのみ行われます。
+
+[pytest-watch](https://github.com/joeyespo/pytest-watch) は、この機能の代替実装です。
+
+### Skip a test module
+
+特定のテストモジュールを除外してすべてのテストモジュールを実行したい場合、実行するテストの明示的なリストを指定することができます。例えば、`test_modeling_*.py` テストを除外してすべてを実行するには次のようにします:
+
+```bash
+pytest *ls -1 tests/*py | grep -v test_modeling*
+```
+
+### Clearing state
+
+CIビルドおよび速度に対する隔離が重要な場合(キャッシュに対して)、キャッシュをクリアする必要があります:
+
+```bash
+pytest --cache-clear tests
+```
+
+### Running tests in parallel
+
+前述のように、`make test` は `pytest-xdist` プラグインを介してテストを並列実行します(`-n X` 引数、例: `-n 2` で2つの並列ジョブを実行)。
+
+`pytest-xdist` の `--dist=` オプションを使用すると、テストがどのようにグループ化されるかを制御できます。`--dist=loadfile` は同じファイルにあるテストを同じプロセスに配置します。
+
+テストの実行順序が異なり予測不可能であるため、`pytest-xdist` を使用してテストスイートを実行すると失敗が発生する場合(つまり、いくつかの未検出の連動テストがある場合)、[pytest-replay](https://github.com/ESSS/pytest-replay) を使用してテストを同じ順序で再生し、その後、失敗するシーケンスを最小限にするのに役立ちます。
+
+### Test order and repetition
+
+潜在的な相互依存性や状態に関連するバグ(ティアダウン)を検出するために、テストを複数回、連続して、ランダムに、またはセットで繰り返すことは有用です。そして、単純な複数回の繰り返しは、DLのランダム性によって明らかになるいくつかの問題を検出するのに役立ちます。
+
+#### Repeat tests
+
+- [pytest-flakefinder](https://github.com/dropbox/pytest-flakefinder):
+
+```bash
+pip install pytest-flakefinder
+```
+
+そして、すべてのテストを複数回実行します (デフォルトでは 50 回)。
+
+```bash
+pytest --flake-finder --flake-runs=5 tests/test_failing_test.py
+```
+
+
+
+このプラグインは、`pytest-xdist` の `-n` フラグでは動作しません。
+
+
+
+
+
+
+別のプラグイン `pytest-repeat` もありますが、これは `unittest` では動作しません。
+
+
+
+#### Run tests in a random order
+
+```bash
+pip install pytest-random-order
+```
+
+重要: `pytest-random-order` が存在すると、テストは自動的にランダム化されます。設定の変更や変更は必要ありません。
+コマンドラインオプションは必須です。
+
+前に説明したように、これにより、結合されたテスト (1 つのテストの状態が別のテストの状態に影響を与える) の検出が可能になります。いつ
+`pytest-random-order` がインストールされていると、そのセッションに使用されたランダム シードが出力されます。例:
+
+
+```bash
+pytest tests
+[...]
+Using --random-order-bucket=module
+Using --random-order-seed=573663
+```
+
+そのため、指定された特定のシーケンスが失敗した場合、その正確なシードを追加することでそれを再現できます。例:
+
+```bash
+pytest --random-order-seed=573663
+[...]
+Using --random-order-bucket=module
+Using --random-order-seed=573663
+```
+
+特定のテストのリストを使用しない場合、またはまったくリストを使用しない場合、同じテストの正確な順序を再現します。テストのリストを手動で絞り込み始めると、シードに依存せず、テストが失敗した正確な順序で手動でリストを指定する必要があります。これには、`--random-order-bucket=none` を使用してランダム化を無効にするようpytestに指示する必要があります。例えば、次のようにします:
+
+
+```bash
+pytest --random-order-bucket=none tests/test_a.py tests/test_c.py tests/test_b.py
+```
+
+すべてのテストのシャッフルを無効にするには:
+
+```bash
+pytest --random-order-bucket=none
+```
+
+デフォルトでは、`--random-order-bucket=module` が暗黙的に適用され、モジュールレベルでファイルをシャッフルします。また、`class`、`package`、`global`、および`none` レベルでシャッフルすることもできます。詳細については、その[ドキュメンテーション](https://github.com/jbasko/pytest-random-order)を参照してください。
+
+別のランダム化の代替手段は、[`pytest-randomly`](https://github.com/pytest-dev/pytest-randomly) です。このモジュールは非常に似た機能/インターフェースを持っていますが、`pytest-random-order` で利用可能なバケットモードを持っていません。インストール後に自動的に有効になるという同じ問題があります。
+
+### Look and feel variations
+
+#### pytest-sugar
+
+[pytest-sugar](https://github.com/Frozenball/pytest-sugar) は、外観と操作性を向上させ、プログレスバーを追加し、即座に失敗したテストとアサーションを表示するプラグインです。インストール後に自動的にアクティブ化されます。
+
+```bash
+pip install pytest-sugar
+```
+
+
+これを使用せずにテストを実行するには、次を実行します。
+
+```bash
+pytest -p no:sugar
+```
+
+またはアンインストールします。
+
+#### Report each sub-test name and its progress
+
+`pytest` による単一またはグループのテストの場合 (`pip install pytest-pspec` の後):
+
+
+```bash
+pytest --pspec tests/test_optimization.py
+```
+
+
+#### Instantly shows failed tests
+
+[pytest-instafail](https://github.com/pytest-dev/pytest-instafail) では、失敗とエラーが即座に表示されます。
+テストセッションが終了するまで待機します。
+
+```bash
+pip install pytest-instafail
+```
+
+```bash
+pytest --instafail
+```
+
+### To GPU or not to GPU
+
+GPU が有効な設定で、CPU のみモードでテストするには、`CUDA_VISIBLE_DEVICES=""`を追加します。
+
+```bash
+CUDA_VISIBLE_DEVICES="" pytest tests/utils/test_logging.py
+```
+
+
+または、複数の GPU がある場合は、`pytest` でどれを使用するかを指定できます。たとえば、
+2 番目の GPU GPU `0` と `1` がある場合は、次を実行できます。
+
+```bash
+CUDA_VISIBLE_DEVICES="1" pytest tests/utils/test_logging.py
+```
+
+これは、異なるGPUで異なるタスクを実行したい場合に便利です。
+
+一部のテストはCPUのみで実行する必要があり、他のテストはCPU、GPU、またはTPUで実行する必要があり、また別のテストは複数のGPUで実行する必要があります。次のスキップデコレーターは、テストのCPU/GPU/TPUに関する要件を設定するために使用されます:
+
+- `require_torch` - このテストはtorchの下でのみ実行されます。
+- `require_torch_gpu` - `require_torch` に加えて、少なくとも1つのGPUが必要です。
+- `require_torch_multi_gpu` - `require_torch` に加えて、少なくとも2つのGPUが必要です。
+- `require_torch_non_multi_gpu` - `require_torch` に加えて、0または1つのGPUが必要です。
+- `require_torch_up_to_2_gpus` - `require_torch` に加えて、0、1、または2つのGPUが必要です。
+- `require_torch_xla` - `require_torch` に加えて、少なくとも1つのTPUが必要です。
+
+以下の表にGPUの要件を示します:
+
+| n gpus | decorator |
+|--------+--------------------------------|
+| `>= 0` | `@require_torch` |
+| `>= 1` | `@require_torch_gpu` |
+| `>= 2` | `@require_torch_multi_gpu` |
+| `< 2` | `@require_torch_non_multi_gpu` |
+| `< 3` | `@require_torch_up_to_2_gpus` |
+
+
+たとえば、使用可能な GPU が 2 つ以上あり、pytorch がインストールされている場合にのみ実行する必要があるテストを次に示します。
+
+
+```python no-style
+@require_torch_multi_gpu
+def test_example_with_multi_gpu():
+```
+
+テストに `tensorflow` が必要な場合は、`require_tf` デコレータを使用します。例えば:
+
+```python no-style
+@require_tf
+def test_tf_thing_with_tensorflow():
+```
+
+これらのデコレータは積み重ねることができます。たとえば、テストが遅く、pytorch で少なくとも 1 つの GPU が必要な場合は、次のようになります。
+設定方法:
+
+```python no-style
+@require_torch_gpu
+@slow
+def test_example_slow_on_gpu():
+```
+
+`@parametrized` のような一部のデコレータはテスト名を書き換えるため、`@require_*` スキップ デコレータをリストする必要があります。
+最後にそれらが正しく動作するようにします。正しい使用例は次のとおりです
+
+```python no-style
+@parameterized.expand(...)
+@require_torch_multi_gpu
+def test_integration_foo():
+```
+
+この順序の問題は `@pytest.mark.parametrize` には存在しません。最初または最後に配置しても、それでも問題は解決されます。
+仕事。ただし、それは非単体テストでのみ機能します。
+
+内部テスト:
+
+- 利用可能な GPU の数:
+
+```python
+from transformers.testing_utils import get_gpu_count
+
+n_gpu = get_gpu_count() # works with torch and tf
+```
+
+### Testing with a specific PyTorch backend or device
+
+特定のtorchデバイスでテストスイートを実行するには、`TRANSFORMERS_TEST_DEVICE="$device"` を追加します。ここで `$device` は対象のバックエンドです。例えば、CPUでテストするには以下のようにします:
+
+```bash
+TRANSFORMERS_TEST_DEVICE="cpu" pytest tests/utils/test_logging.py
+```
+
+この変数は、`mps`などのカスタムまたはあまり一般的ではない PyTorch バックエンドをテストするのに役立ちます。また、特定の GPU をターゲットにしたり、CPU 専用モードでテストしたりすることで、`CUDA_VISIBLE_DEVICES`と同じ効果を達成するために使用することもできます。
+
+特定のデバイスでは、初めて「torch」をインポートした後、追加のインポートが必要になります。これは、環境変数 `TRANSFORMERS_TEST_BACKEND` を使用して指定できます。
+
+```bash
+TRANSFORMERS_TEST_BACKEND="torch_npu" pytest tests/utils/test_logging.py
+```
+
+### Distributed training
+
+`pytest` は直接的に分散トレーニングを処理することはできません。試みると、サブプロセスは正しい処理を行わず、自分自身が `pytest` であると思い込んでテストスイートをループで実行し続けます。ただし、通常のプロセスを生成し、それから複数のワーカーを生成し、IOパイプを管理するプロセスを生成すれば機能します。
+
+これを使用するいくつかのテストがあります:
+
+- [test_trainer_distributed.py](https://github.com/huggingface/transformers/tree/main/tests/trainer/test_trainer_distributed.py)
+- [test_deepspeed.py](https://github.com/huggingface/transformers/tree/main/tests/deepspeed/test_deepspeed.py)
+
+実行ポイントにすぐに移動するには、これらのテスト内で `execute_subprocess_async` 呼び出しを検索してください。
+
+これらのテストを実行するには、少なくとも2つのGPUが必要です:
+
+```bash
+CUDA_VISIBLE_DEVICES=0,1 RUN_SLOW=1 pytest -sv tests/test_trainer_distributed.py
+```
+
+### Output capture
+
+テストの実行中に、`stdout` および `stderr` に送信された出力はキャプチャされます。テストまたはセットアップメソッドが失敗した場合、通常、それに対応するキャプチャされた出力が失敗のトレースバックと共に表示されます。
+
+出力のキャプチャを無効にし、`stdout` と `stderr` を通常通りに取得するには、`-s` または `--capture=no` を使用してください:
+
+これらのテストを実行するには少なくとも2つのGPUが必要です:
+
+```bash
+pytest -s tests/utils/test_logging.py
+```
+
+テスト結果を JUnit 形式の出力に送信するには:
+
+```bash
+py.test tests --junitxml=result.xml
+```
+
+### Color control
+
+色を持たないようにする(例:黄色のテキストを白い背景に表示すると読みにくいです):
+
+
+```bash
+pytest --color=no tests/utils/test_logging.py
+```
+
+### Sending test report to online pastebin service
+
+テスト失敗ごとに URL を作成します。
+
+
+```bash
+pytest --pastebin=failed tests/utils/test_logging.py
+```
+
+これにより、テスト実行情報がリモートのPasteサービスに送信され、各エラーに対してURLが提供されます。通常通りテストを選択するか、たとえば特定のエラーのみを送信したい場合は `-x` を追加で指定できます。
+
+テストセッション全体のログに対するURLを作成する方法:
+
+
+```bash
+pytest --pastebin=all tests/utils/test_logging.py
+```
+
+## Writing tests
+
+🤗 transformersのテストは `unittest` を基にしていますが、 `pytest` で実行されるため、ほとんどの場合、両方のシステムの機能を使用できます。
+
+[こちら](https://docs.pytest.org/en/stable/unittest.html)でサポートされている機能を読むことができますが、重要なことは、ほとんどの `pytest` のフィクスチャが動作しないことです。パラメータ化も同様ですが、似たような方法で動作する `parameterized` モジュールを使用しています。
+
+### Parametrization
+
+同じテストを異なる引数で複数回実行する必要があることがよくあります。これはテスト内部から行うこともできますが、その場合、そのテストを単一の引数セットで実行する方法はありません。
+
+
+```python
+# test_this1.py
+import unittest
+from parameterized import parameterized
+
+
+class TestMathUnitTest(unittest.TestCase):
+ @parameterized.expand(
+ [
+ ("negative", -1.5, -2.0),
+ ("integer", 1, 1.0),
+ ("large fraction", 1.6, 1),
+ ]
+ )
+ def test_floor(self, name, input, expected):
+ assert_equal(math.floor(input), expected)
+```
+
+デフォルトでは、このテストは3回実行され、それぞれの実行で `test_floor` の最後の3つの引数がパラメータリストの対応する引数に割り当てられます。
+
+そして、`negative` と `integer` パラメータのセットのみを実行することもできます:
+
+```bash
+pytest -k "negative and integer" tests/test_mytest.py
+```
+
+または、`Negative`のサブテストを除くすべての場合、次のようになります。
+
+```bash
+pytest -k "not negative" tests/test_mytest.py
+```
+
+`-k` フィルターを使用することに加えて、各サブテストの正確な名前を調べ、その正確な名前を使用して任意のサブテストまたはすべてのサブテストを実行することができます。
+
+
+```bash
+pytest test_this1.py --collect-only -q
+```
+
+すると次のものがリストされます:
+
+```bash
+test_this1.py::TestMathUnitTest::test_floor_0_negative
+test_this1.py::TestMathUnitTest::test_floor_1_integer
+test_this1.py::TestMathUnitTest::test_floor_2_large_fraction
+```
+
+
+したがって、2 つの特定のサブテストのみを実行できるようになりました。
+
+```bash
+pytest test_this1.py::TestMathUnitTest::test_floor_0_negative test_this1.py::TestMathUnitTest::test_floor_1_integer
+```
+
+`transformers`の開発者依存関係にすでに含まれているモジュール[parameterized](https://pypi.org/project/parameterized/) は、`unittests` と `pytest` テストの両方で機能します。
+
+ただし、テストが `unittest` でない場合、`pytest.mark.parametrize` を使用することができます(または既存のテストのいくつかで、主に `examples` の下で使用されているのを見ることができます)。
+
+次に、同じ例を示しますが、今度は `pytest` の `parametrize` マーカーを使用しています:
+
+
+```python
+# test_this2.py
+import pytest
+
+
+@pytest.mark.parametrize(
+ "name, input, expected",
+ [
+ ("negative", -1.5, -2.0),
+ ("integer", 1, 1.0),
+ ("large fraction", 1.6, 1),
+ ],
+)
+def test_floor(name, input, expected):
+ assert_equal(math.floor(input), expected)
+```
+
+`parameterized` と同様に、`pytest.mark.parametrize` を使用すると、`-k` フィルタが役立たない場合でも、サブテストの実行を細かく制御できます。ただし、このパラメータ化関数はサブテストの名前をわずかに異なるものにします。以下にその例を示します:
+
+
+```bash
+pytest test_this2.py --collect-only -q
+```
+
+すると次のものがリストされます:
+
+```bash
+test_this2.py::test_floor[integer-1-1.0]
+test_this2.py::test_floor[negative--1.5--2.0]
+test_this2.py::test_floor[large fraction-1.6-1]
+```
+
+これで、特定のテストのみを実行できるようになりました。
+
+```bash
+pytest test_this2.py::test_floor[negative--1.5--2.0] test_this2.py::test_floor[integer-1-1.0]
+```
+
+前の例と同様に。
+
+### Files and directories
+
+テストの中で、現在のテストファイルからの相対位置を知る必要があることがよくあります。しかし、これは簡単なことではありません。なぜなら、テストは複数のディレクトリから呼び出されるか、異なる深さのサブディレクトリに存在することがあるからです。`transformers.test_utils.TestCasePlus` というヘルパークラスは、すべての基本パスを整理し、簡単にアクセスできるようにすることで、この問題を解決します。
+
+- `pathlib` オブジェクト(すべて完全に解決されたもの):
+
+ - `test_file_path` - 現在のテストファイルのパス、つまり `__file__`
+ - `test_file_dir` - 現在のテストファイルを含むディレクトリ
+ - `tests_dir` - `tests` テストスイートのディレクトリ
+ - `examples_dir` - `examples` テストスイートのディレクトリ
+ - `repo_root_dir` - リポジトリのディレクトリ
+ - `src_dir` - `transformers` サブディレクトリが存在する場所
+
+- パスの文字列表現――上記と同じですが、これらは `pathlib` オブジェクトではなく文字列としてパスを返します:
+
+ - `test_file_path_str`
+ - `test_file_dir_str`
+ - `tests_dir_str`
+ - `examples_dir_str`
+ - `repo_root_dir_str`
+ - `src_dir_str`
+
+これらを使用し始めるには、テストが `transformers.test_utils.TestCasePlus` のサブクラスに存在することを確認するだけです。例:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class PathExampleTest(TestCasePlus):
+ def test_something_involving_local_locations(self):
+ data_dir = self.tests_dir / "fixtures/tests_samples/wmt_en_ro"
+```
+
+もし、`pathlib` を介してパスを操作する必要がない場合、または単に文字列としてパスが必要な場合は、`pathlib` オブジェクトに `str()` を呼び出すか、`_str` で終わるアクセサを使用できます。例:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class PathExampleTest(TestCasePlus):
+ def test_something_involving_stringified_locations(self):
+ examples_dir = self.examples_dir_str
+```
+
+### Temporary files and directories
+
+一意の一時ファイルとディレクトリの使用は、並列テストの実行には欠かせません。これにより、テストがお互いのデータを上書きしないようにします。また、これらを作成した各テストの終了時に一時ファイルとディレクトリが削除されることを望みます。そのため、これらのニーズを満たすパッケージである `tempfile` のようなパッケージの使用は重要です。
+
+しかし、テストのデバッグ時には、一時ファイルやディレクトリに何が格納されているかを確認できる必要があり、テストを再実行するたびにランダムに変更されないその正確なパスを知りたいと思います。
+
+`transformers.test_utils.TestCasePlus` というヘルパークラスは、このような目的に最適です。これは `unittest.TestCase` のサブクラスであるため、テストモジュールで簡単に継承することができます。
+
+以下はその使用例です:
+
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class ExamplesTests(TestCasePlus):
+ def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+```
+
+このコードはユニークな一時ディレクトリを作成し、`tmp_dir` をその場所に設定します。
+
+- ユニークな一時ディレクトリを作成します:
+
+```python
+def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+```
+
+`tmp_dir` には、作成された一時ディレクトリへのパスが含まれます。期間終了後は自動的に削除されます
+テスト。
+
+- 任意の一時ディレクトリを作成し、テストの開始前にそれが空であることを確認し、テスト後には空にしないでください。
+
+```python
+def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir("./xxx")
+```
+
+これは、特定のディレクトリを監視し、前のテストがそこにデータを残さないことを確認したい場合に、デバッグに役立ちます。
+
+- `before` と `after` 引数を直接オーバーライドすることで、デフォルトの動作をオーバーライドできます。以下のいずれかの動作に導きます:
+
+ - `before=True`:テストの開始時に常に一時ディレクトリがクリアされます。
+ - `before=False`:一時ディレクトリが既に存在する場合、既存のファイルはそのままになります。
+ - `after=True`:テストの終了時に常に一時ディレクトリが削除されます。
+ - `after=False`:テストの終了時に常に一時ディレクトリはそのままになります。
+
+
+
+`rm -r`の相当を安全に実行するために、明示的な `tmp_dir` が使用される場合、プロジェクトリポジトリのチェックアウトのサブディレクトリのみが許可されます。誤って `/tmp` などのファイルシステムの重要な部分が削除されないように、常に `./` から始まるパスを渡してください。
+
+
+
+
+
+各テストは複数の一時ディレクトリを登録でき、要求がない限りすべて自動で削除されます。
+
+
+
+### Temporary sys.path override
+
+別のテストからインポートするために一時的に `sys.path` をオーバーライドする必要がある場合、`ExtendSysPath` コンテキストマネージャを使用できます。例:
+
+
+```python
+import os
+from transformers.testing_utils import ExtendSysPath
+
+bindir = os.path.abspath(os.path.dirname(__file__))
+with ExtendSysPath(f"{bindir}/.."):
+ from test_trainer import TrainerIntegrationCommon # noqa
+```
+
+### Skipping tests
+
+これは、バグが見つかり、新しいテストが作成された場合であっても、バグがまだ修正されていない場合に役立ちます。メインリポジトリにコミットできるようにするには、`make test` の実行中にそれをスキップする必要があります。
+
+メソッド:
+
+- **skip** は、テストが特定の条件が満たされた場合にのみパスすることを期待しており、それ以外の場合は pytest がテストの実行をスキップします。一般的な例は、Windows専用のテストを非Windowsプラットフォームでスキップする場合、または現在利用できない外部リソースに依存するテストをスキップする場合です(例: データベースが利用できない場合)。
+
+- **xfail** は、何らかの理由でテストが失敗することを期待しています。一般的な例は、まだ実装されていない機能のテストや、まだ修正されていないバグのテストです。テストが予想される失敗にもかかわらずパスした場合(pytest.mark.xfailでマークされたテスト)、それはxpassとしてテストサマリーに報告されます。
+
+これらの2つの間の重要な違いの1つは、`skip` はテストを実行しない点であり、`xfail` は実行します。したがって、バグのあるコードが他のテストに影響を与える場合は、`xfail` を使用しないでください。
+
+#### Implementation
+
+- テスト全体を無条件にスキップする方法は次のとおりです:
+
+
+```python no-style
+@unittest.skip(reason="this bug needs to be fixed")
+def test_feature_x():
+```
+
+または pytest 経由:
+
+```python no-style
+@pytest.mark.skip(reason="this bug needs to be fixed")
+```
+
+または `xfail` の方法:
+
+```python no-style
+@pytest.mark.xfail
+def test_feature_x():
+```
+
+
+- テスト内の内部チェックに基づいてテストをスキップする方法は次のとおりです。
+
+```python
+def test_feature_x():
+ if not has_something():
+ pytest.skip("unsupported configuration")
+```
+
+またはモジュール全体:
+
+```python
+import pytest
+
+if not pytest.config.getoption("--custom-flag"):
+ pytest.skip("--custom-flag is missing, skipping tests", allow_module_level=True)
+```
+
+または `xfail` の方法:
+
+```python
+def test_feature_x():
+ pytest.xfail("expected to fail until bug XYZ is fixed")
+```
+
+- 一部のインポートが欠落している場合にモジュール内のすべてのテストをスキップする方法は次のとおりです。
+
+```python
+docutils = pytest.importorskip("docutils", minversion="0.3")
+```
+
+- 条件に基づいてテストをスキップします。
+
+```python no-style
+@pytest.mark.skipif(sys.version_info < (3,6), reason="requires python3.6 or higher")
+def test_feature_x():
+```
+
+または:
+
+```python no-style
+@unittest.skipIf(torch_device == "cpu", "Can't do half precision")
+def test_feature_x():
+```
+
+
+またはモジュール全体をスキップします。
+
+```python no-style
+@pytest.mark.skipif(sys.platform == 'win32', reason="does not run on windows")
+class TestClass():
+ def test_feature_x(self):
+```
+
+詳細、例、および方法についての詳細は[こちら](https://docs.pytest.org/en/latest/skipping.html)を参照してください。
+
+### Slow tests
+
+テストライブラリは着実に成長しており、テストの一部は数分かかります。そのため、CIでテストスイートの完了を待つのは1時間待つ余裕がないことがあります。したがって、いくつかの例外を除いて、遅いテストは以下の例のようにマークすべきです:
+
+
+```python no-style
+from transformers.testing_utils import slow
+@slow
+def test_integration_foo():
+```
+
+
+テストが`@slow`としてマークされたら、そのようなテストを実行するには、環境変数 `RUN_SLOW=1`を設定します。例:
+
+```bash
+RUN_SLOW=1 pytest tests
+```
+
+`@parameterized` のようなデコレータはテスト名を書き換えるため、`@slow` および他のスキップデコレータ `@require_*` は正しく動作するためには、最後にリストアップする必要があります。以下は正しい使用例の一例です:
+
+
+```python no-style
+@parameterized.expand(...)
+@slow
+def test_integration_foo():
+```
+
+このドキュメントの冒頭で説明したように、遅いテストは定期的なスケジュールに従って実行され、PRのCIチェックでは実行されません。そのため、一部の問題がPRの提出時に見落とされ、マージされる可能性があります。そのような問題は次回のスケジュールされたCIジョブで検出されます。しかし、それはまた、PRを提出する前に自分のマシンで遅いテストを実行する重要性を意味しています。
+
+どのテストを遅いテストとしてマークすべきかを選択するための、おおまかな意思決定メカニズムが次に示されています:
+
+- テストがライブラリの内部コンポーネントの1つに焦点を当てている場合(例: モデリングファイル、トークン化ファイル、パイプライン)、そのテストは遅いテストスイートで実行する必要があります。それがライブラリの他の側面、たとえばドキュメンテーションや例に焦点を当てている場合、それらのテストは遅いテストスイートで実行する必要があります。そして、このアプローチを洗練させるために例外を設ける必要があります。
+
+- 重いウェイトセットや約50MB以上のデータセットをダウンロードする必要があるすべてのテスト(例: モデル統合テスト、トークナイザ統合テスト、パイプライン統合テスト)は遅いテストとして設定する必要があります。新しいモデルを追加する場合、統合テスト用にランダムなウェイトを持つ小さなバージョンを作成し、ハブにアップロードする必要があります。これについては以下の段落で詳しく説明します。
+
+- 特に高速化されていないトレーニングを行う必要があるすべてのテストは遅いテストとして設定する必要があります。
+
+- 一部の「遅い」であるべきでないテストが非常に遅い場合、およびそれらを `@slow` として設定する必要がある場合には例外を導入できます。大容量のファイルをディスクに保存および読み込みする自動モデリングテストは、`@slow` としてマークされたテストの良い例です。
+
+- CIで1秒未満でテストが完了する場合(ダウンロードを含む)、それは通常のテストであるべきです。
+
+すべての非遅いテストは、さまざまな内部要素を完全にカバーする必要がありますが、高速である必要があります。たとえば、特別に作成された小さなモデル(レイヤー数が最小限で、語彙サイズが小さいなど)を使用して、かなりのカバレッジを実現できます。その後、`@slow` テストでは大規模な遅いモデルを使用して質的なテストを実行できます。これらを使用するには、以下のように *tiny* モデルを探してください:
+
+
+```bash
+grep tiny tests examples
+```
+
+[スクリプトの例](https://github.com/huggingface/transformers/tree/main/scripts/fsmt/fsmt-make-tiny-model.py)があり、これにより tiny-wmt19-en-de のような小さなモデルが作成されます。特定のモデルのアーキテクチャに簡単に調整できます。
+
+実行時間を誤って測定することが簡単です。たとえば、巨大なモデルのダウンロードに関するオーバーヘッドがある場合、ローカルでテストするとダウンロードされたファイルがキャッシュされ、ダウンロード時間が計測されなくなります。したがって、CIログの実行速度レポート(`pytest --durations=0 tests` の出力)を確認してください。
+
+このレポートは、遅いテストとしてマークされていない遅い外れ値や、高速に書き直す必要があるテストを見つけるのにも役立ちます。テストスイートがCIで遅くなり始めた場合、このレポートのトップリストには最も遅いテストが表示されます。
+
+### Testing the stdout/stderr output
+
+`stdout` および/または `stderr` に書き込む関数をテストするために、テストは `pytest` の [capsys システム](https://docs.pytest.org/en/latest/capture.html) を使用してこれらのストリームにアクセスできます。以下はその方法です:
+
+
+```python
+import sys
+
+
+def print_to_stdout(s):
+ print(s)
+
+
+def print_to_stderr(s):
+ sys.stderr.write(s)
+
+
+def test_result_and_stdout(capsys):
+ msg = "Hello"
+ print_to_stdout(msg)
+ print_to_stderr(msg)
+ out, err = capsys.readouterr() # consume the captured output streams
+ # optional: if you want to replay the consumed streams:
+ sys.stdout.write(out)
+ sys.stderr.write(err)
+ # test:
+ assert msg in out
+ assert msg in err
+```
+
+
+そしてもちろん、ほとんどの場合、`stderr`は例外の一部として提供されるため、そのような場合には try/excel を使用する必要があります。
+ケース:
+
+```python
+def raise_exception(msg):
+ raise ValueError(msg)
+
+
+def test_something_exception():
+ msg = "Not a good value"
+ error = ""
+ try:
+ raise_exception(msg)
+ except Exception as e:
+ error = str(e)
+ assert msg in error, f"{msg} is in the exception:\n{error}"
+```
+
+
+stdout をキャプチャするもう 1 つのアプローチは、`contextlib.redirect_stdout`を使用することです。
+
+```python
+from io import StringIO
+from contextlib import redirect_stdout
+
+
+def print_to_stdout(s):
+ print(s)
+
+
+def test_result_and_stdout():
+ msg = "Hello"
+ buffer = StringIO()
+ with redirect_stdout(buffer):
+ print_to_stdout(msg)
+ out = buffer.getvalue()
+ # optional: if you want to replay the consumed streams:
+ sys.stdout.write(out)
+ # test:
+ assert msg in out
+```
+
+stdout をキャプチャする際の重要な潜在的な問題は、通常の `print` でこれまでに出力された内容をリセットする可能性がある `\r` 文字が含まれている可能性があることです。`pytest` 自体には問題はありませんが、`pytest -s` ではこれらの文字がバッファに含まれるため、`-s` ありとなしでテストを実行できるようにするには、`re.sub(r'~.*\r', '', buf, 0, re.M)` を使用してキャプチャされた出力に対して追加のクリーンアップを行う必要があります。
+
+しかし、その後、`\r` が含まれているかどうかにかかわらず、すべての操作を自動的に処理するヘルパーコンテキストマネージャラッパーがあります。したがって、次のように簡単に行えます:
+
+
+```python
+from transformers.testing_utils import CaptureStdout
+
+with CaptureStdout() as cs:
+ function_that_writes_to_stdout()
+print(cs.out)
+```
+
+完全なテスト例は次のとおりです。
+
+```python
+from transformers.testing_utils import CaptureStdout
+
+msg = "Secret message\r"
+final = "Hello World"
+with CaptureStdout() as cs:
+ print(msg + final)
+assert cs.out == final + "\n", f"captured: {cs.out}, expecting {final}"
+```
+
+`stderr` をキャプチャしたい場合は、代わりに `CaptureStderr` クラスを使用してください。
+
+```python
+from transformers.testing_utils import CaptureStderr
+
+with CaptureStderr() as cs:
+ function_that_writes_to_stderr()
+print(cs.err)
+```
+
+両方のストリームを一度にキャプチャする必要がある場合は、親の `CaptureStd` クラスを使用します。
+
+```python
+from transformers.testing_utils import CaptureStd
+
+with CaptureStd() as cs:
+ function_that_writes_to_stdout_and_stderr()
+print(cs.err, cs.out)
+```
+
+
+また、テストの問題のデバッグを支援するために、デフォルトで、これらのコンテキスト マネージャーは終了時にキャプチャされたストリームを自動的に再生します。
+文脈から。
+
+### Capturing logger stream
+
+ロガーの出力を検証する必要がある場合は、`CaptureLogger`を使用できます。
+
+```python
+from transformers import logging
+from transformers.testing_utils import CaptureLogger
+
+msg = "Testing 1, 2, 3"
+logging.set_verbosity_info()
+logger = logging.get_logger("transformers.models.bart.tokenization_bart")
+with CaptureLogger(logger) as cl:
+ logger.info(msg)
+assert cl.out, msg + "\n"
+```
+
+### Testing with environment variables
+
+特定のテストで環境変数の影響をテストしたい場合は、ヘルパー デコレータを使用できます。
+`transformers.testing_utils.mockenv`
+
+```python
+from transformers.testing_utils import mockenv
+
+
+class HfArgumentParserTest(unittest.TestCase):
+ @mockenv(TRANSFORMERS_VERBOSITY="error")
+ def test_env_override(self):
+ env_level_str = os.getenv("TRANSFORMERS_VERBOSITY", None)
+```
+
+場合によっては、外部プログラムを呼び出す必要があるため、`os.environ` に`PYTHONPATH`を設定してインクルードする必要があります。
+複数のローカル パス。ヘルパー クラス `transformers.test_utils.TestCasePlus` が役に立ちます。
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class EnvExampleTest(TestCasePlus):
+ def test_external_prog(self):
+ env = self.get_env()
+ # now call the external program, passing `env` to it
+```
+
+テストファイルが `tests` テストスイートまたは `examples` のどちらにあるかに応じて
+`env[PYTHONPATH]` を使用して、これら 2 つのディレクトリのいずれかを含めます。また、テストが確実に行われるようにするための `src` ディレクトリも含めます。
+現在のリポジトリに対して実行され、最後に、テストが実行される前にすでに設定されていた `env[PYTHONPATH]` を使用して実行されます。
+何かあれば呼ばれます。
+
+このヘルパー メソッドは `os.environ` オブジェクトのコピーを作成するため、元のオブジェクトはそのまま残ります。
+
+
+### Getting reproducible results
+
+状況によっては、テストのランダム性を削除したい場合があります。同一の再現可能な結果セットを取得するには、
+シードを修正する必要があります:
+
+```python
+seed = 42
+
+# python RNG
+import random
+
+random.seed(seed)
+
+# pytorch RNGs
+import torch
+
+torch.manual_seed(seed)
+torch.backends.cudnn.deterministic = True
+if torch.cuda.is_available():
+ torch.cuda.manual_seed_all(seed)
+
+# numpy RNG
+import numpy as np
+
+np.random.seed(seed)
+
+# tf RNG
+tf.random.set_seed(seed)
+```
+
+
+### Debugging tests
+
+警告が発生した時点でデバッガーを開始するには、次の手順を実行します。
+
+```bash
+pytest tests/utils/test_logging.py -W error::UserWarning --pdb
+```
+
+## Working with github actions workflows
+
+セルフプッシュのワークフローCIジョブをトリガーするには、以下の手順を実行する必要があります:
+
+1. `transformers` のリモートリポジトリで新しいブランチを作成します(フォークではなく、元のリポジトリで行います)。
+2. ブランチの名前は `ci_` または `ci-` で始まる必要があります(`main` もトリガーしますが、`main` ではPRを作成できません)。また、特定のパスでのみトリガーされます - このドキュメントが書かれた後に変更された場合に備えて、最新の定義は[こちら](https://github.com/huggingface/transformers/blob/main/.github/workflows/self-push.yml)の *push:* にあります。
+3. このブランチからPRを作成します。
+4. その後、このジョブが[ここ](https://github.com/huggingface/transformers/actions/workflows/self-push.yml)に表示されます。ジョブはバックログがある場合、すぐに実行されないことがあります。
+
+## Testing Experimental CI Features
+
+CI機能のテストは通常のCIの正常な動作に干渉する可能性があるため、新しいCI機能を追加する場合、以下の手順に従う必要があります。
+
+1. テストが必要なものをテストするための新しい専用のジョブを作成します。
+2. 新しいジョブは常に成功する必要があるため、常にグリーン ✓(詳細は以下参照)を表示する必要があります。
+3. さまざまな種類のPR(ユーザーフォークブランチ、非フォークブランチ、github.com UIから直接ファイルを編集するブランチ、さまざまな強制プッシュなど)が実行されるまでいくつかの日間実行し、実験的なジョブのログを監視します(意図的に常にグリーンになるようになっている全体のジョブの緑ではなく)。
+4. すべてが安定していることが明確になったら、新しい変更を既存のジョブに統合します。
+
+このように、CI機能自体の実験が通常のワークフローに干渉しないようにできます。
+
+では、新しいCI機能が開発中である間、ジョブを常に成功させるにはどうすればいいでしょうか?
+
+TravisCIのような一部のCIは `ignore-step-failure` をサポートし、全体のジョブを成功として報告しますが、この文書が作成された時点ではCircleCIとGithub Actionsはそれをサポートしていません。
+
+したがって、以下のワークアラウンドを使用できます:
+
+1. bashスクリプト内で潜在的な失敗を抑制するために実行コマンドの冒頭に `set +euo pipefail` を記述します。
+2. 最後のコマンドは成功する必要があります。たとえば `echo "done"` または単に `true` を使用できます。
+
+以下は例です:
+
+
+
+```yaml
+- run:
+ name: run CI experiment
+ command: |
+ set +euo pipefail
+ echo "setting run-all-despite-any-errors-mode"
+ this_command_will_fail
+ echo "but bash continues to run"
+ # emulate another failure
+ false
+ # but the last command must be a success
+ echo "during experiment do not remove: reporting success to CI, even if there were failures"
+```
+
+
+単純なコマンドの場合は、次のようにすることもできます。
+
+```bash
+cmd_that_may_fail || true
+```
+
+もちろん、結果に満足したら、実験的なステップやジョブを通常のジョブと統合し、`set +euo pipefail` などの追加した要素を削除して、実験的なジョブが通常のCIの動作に干渉しないようにします。
+
+このプロセス全体は、実験的なステップに対して `allow-failure` のようなものを設定し、PRの全体のステータスに影響を与えずに失敗させることができれば、はるかに簡単になったでしょう。しかし、前述の通り、現在はCircleCIとGithub Actionsはこの機能をサポートしていません。
+
+この機能に関しての投票や、CIに特有のスレッドでその進捗状況を確認できます:
+
+- [Github Actions:](https://github.com/actions/toolkit/issues/399)
+- [CircleCI:](https://ideas.circleci.com/ideas/CCI-I-344)
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tf_xla.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tf_xla.md
new file mode 100644
index 0000000000000000000000000000000000000000..1f5a2af1a5a2880268423324f65e8c5780337397
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tf_xla.md
@@ -0,0 +1,179 @@
+
+
+# XLA Integration for TensorFlow Models
+
+[[open-in-colab]]
+
+加速線形代数(Accelerated Linear Algebra)、通称XLAは、TensorFlowモデルのランタイムを高速化するためのコンパイラです。[公式ドキュメント](https://www.tensorflow.org/xla)によれば、XLA(Accelerated Linear Algebra)は線形代数のためのドメイン固有のコンパイラで、TensorFlowモデルを潜在的にソースコードの変更なしで高速化できます。
+
+TensorFlowでXLAを使用するのは簡単です。XLAは`tensorflow`ライブラリ内にパッケージ化されており、[`tf.function`](https://www.tensorflow.org/guide/intro_to_graphs)などのグラフを作成する関数内で`jit_compile`引数を使用してトリガーできます。`fit()`や`predict()`などのKerasメソッドを使用する場合、`model.compile()`に`jit_compile`引数を渡すだけでXLAを有効にできます。ただし、XLAはこれらのメソッドに限定されているわけではありません。任意の`tf.function`を高速化するためにも使用できます。
+
+🤗 Transformers内のいくつかのTensorFlowメソッドは、XLAと互換性があるように書き直されています。これには、[GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2)、[T5](https://huggingface.co/docs/transformers/model_doc/t5)、[OPT](https://huggingface.co/docs/transformers/model_doc/opt)などのテキスト生成モデルや、[Whisper](https://huggingface.co/docs/transformers/model_doc/whisper)などの音声処理モデルも含まれます。
+
+速度向上の具体的な量はモデルに非常に依存しますが、🤗 Transformers内のTensorFlowテキスト生成モデルでは、約100倍の速度向上を確認しています。このドキュメントでは、これらのモデルにXLAを使用して最大のパフォーマンスを得る方法を説明します。また、ベンチマークとXLA統合のデザイン哲学について詳しく学びたい場合の追加リソースへのリンクも提供します。
+
+## Running TF functions with XLA
+
+以下のTensorFlowモデルを考えてみましょう:
+
+
+```py
+import tensorflow as tf
+
+model = tf.keras.Sequential(
+ [tf.keras.layers.Dense(10, input_shape=(10,), activation="relu"), tf.keras.layers.Dense(5, activation="softmax")]
+)
+```
+
+上記のモデルは、次元が`(10, )`の入力を受け入れます。このモデルをフォワードパスで実行するには、次のようにします:
+
+
+```py
+# Generate random inputs for the model.
+batch_size = 16
+input_vector_dim = 10
+random_inputs = tf.random.normal((batch_size, input_vector_dim))
+
+# Run a forward pass.
+_ = model(random_inputs)
+```
+
+XLAでコンパイルされた関数を使用してフォワードパスを実行するには、以下のようにします:
+
+
+```py
+xla_fn = tf.function(model, jit_compile=True)
+_ = xla_fn(random_inputs)
+```
+
+`model`のデフォルトの `call()` 関数はXLAグラフをコンパイルするために使用されます。ただし、XLAにコンパイルしたい他のモデル関数がある場合、それも可能です。以下はその方法です:
+
+
+```py
+my_xla_fn = tf.function(model.my_xla_fn, jit_compile=True)
+```
+
+## Running a TF text generation model with XLA from 🤗 Transformers
+
+🤗 Transformers内でXLAでの高速化された生成を有効にするには、最新バージョンの`transformers`がインストールされている必要があります。次のコマンドを実行してインストールできます:
+
+```bash
+pip install transformers --upgrade
+```
+
+次に、次のコードを実行できます:
+
+
+```py
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+# Will error if the minimal version of Transformers is not installed.
+from transformers.utils import check_min_version
+
+check_min_version("4.21.0")
+
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+input_string = ["TensorFlow is"]
+
+# One line to create an XLA generation function
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+tokenized_input = tokenizer(input_string, return_tensors="tf")
+generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+
+decoded_text = tokenizer.decode(generated_tokens[0], skip_special_tokens=True)
+print(f"Generated -- {decoded_text}")
+# Generated -- TensorFlow is an open-source, open-source, distributed-source application # framework for the
+```
+
+`generate()`でXLAを有効にするのは、たった一行のコードです。コードの残り部分は変更されていません。ただし、XLA固有のいくつかの注意点が上記のコードスニペットにあります。これらに注意する必要があり、XLAがもたらす速度向上を実現するためにそれらを把握することが重要です。次のセクションでこれらについて詳しく説明します。
+
+
+## Gotchas to be aware of
+
+XLAを有効にした関数(上記の`xla_generate()`など)を初めて実行すると、内部で計算グラフを推論しようとしますが、これは時間がかかります。このプロセスは["トレーシング"(tracing)](https://www.tensorflow.org/guide/intro_to_graphs#when_is_a_function_tracing)として知られています。
+
+生成時間が高速ではないことに気付くかもしれません。`xla_generate()`(または他のXLA対応関数)の連続呼び出しでは、関数への入力が最初に計算グラフが構築されたときと同じ形状に従っている場合、計算グラフを推論する必要はありません。これは、入力形状が固定されているモダリティ(例:画像)には問題ありませんが、変数の入力形状モダリティ(例:テキスト)を扱う場合には注意が必要です。
+
+`xla_generate()`が常に同じ入力形状で動作するようにするには、トークナイザを呼び出す際に`padding`引数を指定できます。
+
+```py
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+input_string = ["TensorFlow is"]
+
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+# Here, we call the tokenizer with padding options.
+tokenized_input = tokenizer(input_string, pad_to_multiple_of=8, padding=True, return_tensors="tf")
+
+generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+decoded_text = tokenizer.decode(generated_tokens[0], skip_special_tokens=True)
+print(f"Generated -- {decoded_text}")
+```
+
+これにより、`xla_generate()`への入力が常にトレースされた形状の入力を受け取ることを確認し、生成時間の高速化を実現できます。以下のコードでこれを確認できます:
+
+```py
+import time
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+for input_string in ["TensorFlow is", "TensorFlow is a", "TFLite is a"]:
+ tokenized_input = tokenizer(input_string, pad_to_multiple_of=8, padding=True, return_tensors="tf")
+ start = time.time_ns()
+ generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+ end = time.time_ns()
+ print(f"Execution time -- {(end - start) / 1e6:.1f} ms\n")
+```
+
+Tesla T4 GPUを使用すると、次のような出力が期待されます:
+
+```bash
+Execution time -- 30819.6 ms
+
+Execution time -- 79.0 ms
+
+Execution time -- 78.9 ms
+```
+
+最初の`xla_generate()`呼び出しはトレーシングのために時間がかかりますが、連続する呼び出しは桁違いに高速です。生成オプションのいかなる変更も、再トレーシングを引き起こし、生成時間の遅延を引き起こすことに注意してください。
+
+このドキュメントでは、🤗 Transformersが提供するテキスト生成オプションをすべて網羅していません。高度なユースケースについてはドキュメンテーションを参照することをお勧めします。
+
+## Additional Resources
+
+ここでは、🤗 Transformersと一般的なXLAについてさらに詳しく学びたい場合のいくつかの追加リソースを提供します。
+
+* [このColab Notebook](https://colab.research.google.com/github/huggingface/blog/blob/main/notebooks/91_tf_xla_generate.ipynb)では、XLA対応のエンコーダーデコーダー([T5](https://huggingface.co/docs/transformers/model_doc/t5)など)およびデコーダー専用([GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2)など)テキスト生成モデルを試すための対話型デモが提供されています。
+* [このブログ記事](https://huggingface.co/blog/tf-xla-generate)では、XLA対応モデルの比較ベンチマークの概要と、TensorFlowでのXLAについての友好的な紹介が提供されています。
+* [このブログ記事](https://blog.tensorflow.org/2022/11/how-hugging-face-improved-text-generation-performance-with-xla.html)では、🤗 TransformersのTensorFlowモデルにXLAサポートを追加する際の設計哲学について説明しています。
+* 一般的なXLAとTensorFlowグラフについて詳しく学ぶためのおすすめの投稿:
+ * [XLA: 機械学習用の最適化コンパイラ](https://www.tensorflow.org/xla)
+ * [グラフと`tf.function`の紹介](https://www.tensorflow.org/guide/intro_to_graphs)
+ * [`tf.function`を使用したパフォーマンス向上](https://www.tensorflow.org/guide/function)
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tflite.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tflite.md
new file mode 100644
index 0000000000000000000000000000000000000000..ad3e9a3f484e2ce157a23cf0b58d1854efc8a267
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tflite.md
@@ -0,0 +1,58 @@
+
+
+# Export to TFLite
+
+[TensorFlow Lite](https://www.tensorflow.org/lite/guide)は、モバイルフォン、組み込みシステム、およびモノのインターネット(IoT)デバイスなど、リソースに制約のあるデバイスに機械学習モデルを展開するための軽量なフレームワークです。TFLiteは、計算能力、メモリ、および電力消費が限られているこれらのデバイス上でモデルを効率的に最適化して実行するために設計されています。
+TensorFlow Liteモデルは、`.tflite`ファイル拡張子で識別される特別な効率的なポータブル形式で表されます。
+
+🤗 Optimumは、🤗 TransformersモデルをTFLiteにエクスポートするための機能を`exporters.tflite`モジュールを介して提供しています。サポートされているモデルアーキテクチャのリストについては、[🤗 Optimumのドキュメント](https://huggingface.co/docs/optimum/exporters/tflite/overview)をご参照ください。
+
+モデルをTFLiteにエクスポートするには、必要な依存関係をインストールしてください:
+
+
+```bash
+pip install optimum[exporters-tf]
+```
+
+すべての利用可能な引数を確認するには、[🤗 Optimumドキュメント](https://huggingface.co/docs/optimum/main/en/exporters/tflite/usage_guides/export_a_model)を参照するか、コマンドラインでヘルプを表示してください:
+
+```bash
+optimum-cli export tflite --help
+```
+
+🤗 Hubからモデルのチェックポイントをエクスポートするには、例えば `google-bert/bert-base-uncased` を使用する場合、次のコマンドを実行します:
+
+```bash
+optimum-cli export tflite --model google-bert/bert-base-uncased --sequence_length 128 bert_tflite/
+```
+
+進行状況を示すログが表示され、生成された `model.tflite` が保存された場所も表示されるはずです:
+
+```bash
+Validating TFLite model...
+ -[✓] TFLite model output names match reference model (logits)
+ - Validating TFLite Model output "logits":
+ -[✓] (1, 128, 30522) matches (1, 128, 30522)
+ -[x] values not close enough, max diff: 5.817413330078125e-05 (atol: 1e-05)
+The TensorFlow Lite export succeeded with the warning: The maximum absolute difference between the output of the reference model and the TFLite exported model is not within the set tolerance 1e-05:
+- logits: max diff = 5.817413330078125e-05.
+ The exported model was saved at: bert_tflite
+ ```
+
+上記の例は🤗 Hubからチェックポイントをエクスポートする方法を示しています。ローカルモデルをエクスポートする場合、まずモデルの重みファイルとトークナイザファイルを同じディレクトリ(`local_path`)に保存したことを確認してください。CLIを使用する場合、🤗 Hubのチェックポイント名の代わりに`model`引数に`local_path`を渡します。
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tokenizer_summary.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tokenizer_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..448ad9c871aaa340de9d2b6f954549c8849091d3
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/tokenizer_summary.md
@@ -0,0 +1,179 @@
+
+
+# Summary of the tokenizers
+
+[[open-in-colab]]
+
+このページでは、トークナイゼーションについて詳しく見ていきます。
+
+
+
+[前処理のチュートリアル](preprocessing)で見たように、テキストをトークン化することは、それを単語またはサブワードに分割し、それらをルックアップテーブルを介してIDに変換することです。単語またはサブワードをIDに変換することは簡単ですので、この要約ではテキストを単語またはサブワードに分割する(つまり、テキストをトークナイズする)ことに焦点を当てます。具体的には、🤗 Transformersで使用される3つの主要なトークナイザ、[Byte-Pair Encoding(BPE)](#byte-pair-encoding)、[WordPiece](#wordpiece)、および[SentencePiece](#sentencepiece)を見て、どのモデルがどのトークナイザタイプを使用しているかの例を示します。
+
+各モデルページでは、事前トレーニング済みモデルがどのトークナイザタイプを使用しているかを知るために、関連するトークナイザのドキュメントを確認できます。例えば、[`BertTokenizer`]を見ると、モデルが[WordPiece](#wordpiece)を使用していることがわかります。
+
+## Introduction
+
+テキストをより小さなチャンクに分割することは、見かけ以上に難しいタスクであり、複数の方法があります。例えば、次の文を考えてみましょう。「"Don't you love 🤗 Transformers? We sure do."」
+
+
+
+このテキストをトークン化する簡単な方法は、スペースで分割することです。これにより、以下のようになります:
+
+
+```
+["Don't", "you", "love", "🤗", "Transformers?", "We", "sure", "do."]
+```
+
+これは合理的な第一歩ですが、トークン "Transformers?" と "do." を見ると、句読点が単語 "Transformer" と "do" に結合されていることがわかり、これは最適ではありません。句読点を考慮に入れるべきで、モデルが単語とそれに続く可能性のあるすべての句読点記号の異なる表現を学ばなければならないことを避けるべきです。これにより、モデルが学ばなければならない表現の数が爆発的に増加します。句読点を考慮に入れた場合、例文のトークン化は次のようになります:
+
+
+```
+["Don", "'", "t", "you", "love", "🤗", "Transformers", "?", "We", "sure", "do", "."]
+```
+
+ただし、単語「"Don't"」をトークン化する方法に関しては、不利な側面があります。 「"Don't"」は「"do not"」を表しているため、「["Do", "n't"]」としてトークン化する方が適しています。ここから事柄が複雑になり、各モデルが独自のトークナイザータイプを持つ理由の一部でもあります。テキストをトークン化するために適用するルールに応じて、同じテキストに対して異なるトークナイズされた出力が生成されます。事前トレーニング済みモデルは、トレーニングデータをトークナイズするのに使用されたルールと同じルールでトークナイズされた入力を提供する場合にのみ正常に機能します。
+
+[spaCy](https://spacy.io/)と[Moses](http://www.statmt.org/moses/?n=Development.GetStarted)は、2つの人気のあるルールベースのトークナイザーです。これらを私たちの例に適用すると、*spaCy*と*Moses*は次のような出力を生成します:
+
+```
+["Do", "n't", "you", "love", "🤗", "Transformers", "?", "We", "sure", "do", "."]
+```
+
+空白と句読点のトークン化、およびルールベースのトークン化が使用されていることがわかります。空白と句読点のトークン化、およびルールベースのトークン化は、文を単語に分割することをゆるやかに定義される単語トークン化の例です。テキストをより小さなチャンクに分割するための最も直感的な方法である一方、このトークン化方法は大規模なテキストコーパスに対して問題を引き起こすことがあります。この場合、空白と句読点のトークン化は通常、非常に大きな語彙(すべての一意な単語とトークンのセット)を生成します。例えば、[Transformer XL](model_doc/transformerxl)は空白と句読点のトークン化を使用しており、語彙サイズは267,735です!
+
+このような大きな語彙サイズは、モデルに非常に大きな埋め込み行列を入力および出力レイヤーとして持たせることを強制し、メモリおよび時間の複雑さの増加を引き起こします。一般的に、トランスフォーマーモデルは、特に単一の言語で事前トレーニングされた場合、50,000を超える語彙サイズを持つことはほとんどありません。
+
+したがって、シンプルな空白と句読点のトークン化が不十分な場合、なぜ単に文字単位でトークン化しないのかという疑問が生じますか?
+
+
+
+文字単位のトークン化は非常にシンプルであり、メモリと時間の複雑さを大幅に削減できますが、モデルに意味のある入力表現を学習させることが非常に難しくなります。たとえば、文字「"t"」のための意味のあるコンテキスト独立の表現を学習することは、単語「"today"」のためのコンテキスト独立の表現を学習するよりもはるかに難しいです。そのため、文字単位のトークン化はしばしばパフォーマンスの低下を伴います。したがって、トランスフォーマーモデルは単語レベルと文字レベルのトークン化のハイブリッドである**サブワード**トークン化を使用して、両方の世界の利点を活かします。
+
+## Subword tokenization
+
+
+
+サブワードトークン化アルゴリズムは、頻繁に使用される単語をより小さなサブワードに分割すべきではないが、珍しい単語は意味のあるサブワードに分解されるという原則に依存しています。たとえば、「"annoyingly"」は珍しい単語と見なされ、その単語は「"annoying"」と「"ly"」に分解されるかもしれません。独立した「"annoying"」と「"ly"」はより頻繁に現れますが、「"annoyingly"」の意味は「"annoying"」と「"ly"」の合成的な意味によって保持されます。これは特にトルコ語などの結合言語で役立ちます。ここではサブワードを連結して(ほぼ)任意の長い複雑な単語を形成できます。
+
+サブワードトークン化により、モデルは合理的な語彙サイズを持つことができ、意味のあるコンテキスト独立の表現を学習できます。さらに、サブワードトークン化により、モデルは以前に見たことのない単語を処理し、それらを既知のサブワードに分解することができます。例えば、[`~transformers.BertTokenizer`]は`"I have a new GPU!"`を以下のようにトークン化します:
+
+
+```py
+>>> from transformers import BertTokenizer
+
+>>> tokenizer = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+>>> tokenizer.tokenize("I have a new GPU!")
+["i", "have", "a", "new", "gp", "##u", "!"]
+```
+
+「uncased」モデルを考慮しているため、まず文を小文字に変換しました。トークナイザの語彙に「["i", "have", "a", "new"]」という単語が存在することがわかりますが、「"gpu"」という単語は存在しません。したがって、トークナイザは「"gpu"」を既知のサブワード「["gp"、"##u"]」に分割します。ここで「"##"」は、トークンのデコードまたはトークナイゼーションの逆転のために、トークンの前の部分にスペースなしで接続する必要があることを意味します。
+
+別の例として、[`~transformers.XLNetTokenizer`]は以下のように以前のサンプルテキストをトークン化します:
+
+```py
+>>> from transformers import XLNetTokenizer
+
+>>> tokenizer = XLNetTokenizer.from_pretrained("xlnet/xlnet-base-cased")
+>>> tokenizer.tokenize("Don't you love 🤗 Transformers? We sure do.")
+["▁Don", "'", "t", "▁you", "▁love", "▁", "🤗", "▁", "Transform", "ers", "?", "▁We", "▁sure", "▁do", "."]
+```
+
+これらの「▁」の意味については、[SentencePiece](#sentencepiece)を見るときに詳しく説明します。ご覧の通り、「Transformers」という珍しい単語は、より頻繁に現れるサブワード「Transform」と「ers」に分割されています。
+
+さて、異なるサブワードトークン化アルゴリズムがどのように動作するかを見てみましょう。これらのトークナイゼーションアルゴリズムはすべて、通常は対応するモデルがトレーニングされるコーパスで行われる形式のトレーニングに依存しています。
+
+
+
+### Byte-Pair Encoding(BPE)
+
+Byte-Pair Encoding(BPE)は、[Neural Machine Translation of Rare Words with Subword Units(Sennrich et al., 2015)](https://arxiv.org/abs/1508.07909)で導入されました。BPEは、トレーニングデータを単語に分割するプリトークナイザに依存しています。プリトークナイゼーションは、空白のトークナイゼーションなど、非常に単純なものであることがあります。例えば、[GPT-2](model_doc/gpt2)、[RoBERTa](model_doc/roberta)です。より高度なプリトークナイゼーションには、ルールベースのトークナイゼーション([XLM](model_doc/xlm)、[FlauBERT](model_doc/flaubert)などが大部分の言語にMosesを使用)や、[GPT](model_doc/gpt)(Spacyとftfyを使用してトレーニングコーパス内の各単語の頻度を数える)などが含まれます。
+
+プリトークナイゼーションの後、一意の単語セットが作成され、各単語がトレーニングデータで出現した頻度が決定されます。次に、BPEはベース語彙を作成し、ベース語彙の二つのシンボルから新しいシンボルを形成するためのマージルールを学習します。このプロセスは、語彙が所望の語彙サイズに達するまで続けられます。なお、所望の語彙サイズはトークナイザをトレーニングする前に定義するハイパーパラメータであることに注意してください。
+
+例として、プリトークナイゼーションの後、次のセットの単語とその出現頻度が決定されたと仮定しましょう:
+
+
+```
+("hug", 10), ("pug", 5), ("pun", 12), ("bun", 4), ("hugs", 5)
+```
+
+したがって、ベース語彙は「["b", "g", "h", "n", "p", "s", "u"]」です。すべての単語をベース語彙のシンボルに分割すると、次のようになります:
+
+
+```
+("h" "u" "g", 10), ("p" "u" "g", 5), ("p" "u" "n", 12), ("b" "u" "n", 4), ("h" "u" "g" "s", 5)
+```
+
+その後、BPEは可能なすべてのシンボルペアの頻度を数え、最も頻繁に発生するシンボルペアを選択します。上記の例では、`"h"`の後に`"u"`が15回(`"hug"`の10回、`"hugs"`の5回)出現します。しかし、最も頻繁なシンボルペアは、合計で20回(`"u"`の10回、`"g"`の5回、`"u"`の5回)出現する`"u"`の後に`"g"`が続くシンボルペアです。したがって、トークナイザが最初に学習するマージルールは、`"u"`の後に`"g"`が続くすべての`"u"`シンボルを一緒にグループ化することです。次に、`"ug"`が語彙に追加されます。単語のセットは次になります:
+
+
+```
+("h" "ug", 10), ("p" "ug", 5), ("p" "u" "n", 12), ("b" "u" "n", 4), ("h" "ug" "s", 5)
+```
+
+次に、BPEは次に最も一般的なシンボルペアを識別します。それは「"u"」に続いて「"n"」で、16回出現します。したがって、「"u"」と「"n"」は「"un"」に結合され、語彙に追加されます。次に最も頻度の高いシンボルペアは、「"h"」に続いて「"ug"」で、15回出現します。再びペアが結合され、「hug」が語彙に追加できます。
+
+この段階では、語彙は`["b", "g", "h", "n", "p", "s", "u", "ug", "un", "hug"]`であり、一意の単語のセットは以下のように表されます:
+
+
+```
+("hug", 10), ("p" "ug", 5), ("p" "un", 12), ("b" "un", 4), ("hug" "s", 5)
+```
+
+前提として、Byte-Pair Encoding(BPE)のトレーニングがこの段階で停止すると、学習されたマージルールが新しい単語に適用されます(新しい単語にはベースボキャブラリに含まれていないシンボルが含まれていない限り)。 例えば、単語 "bug" は ["b", "ug"] としてトークン化されますが、"mug" はベースボキャブラリに "m" シンボルが含まれていないため、["", "ug"] としてトークン化されます。 一般的に、"m" のような単一の文字は、トレーニングデータには通常、各文字の少なくとも1つの出現が含まれているため、"" シンボルに置き換えられることはありませんが、絵文字のような非常に特殊な文字の場合には発生する可能性があります。
+
+前述のように、ボキャブラリサイズ、すなわちベースボキャブラリサイズ + マージの回数は選択するハイパーパラメータです。 例えば、[GPT](model_doc/gpt) はベース文字が478文字で、40,000回のマージ後にトレーニングを停止したため、ボキャブラリサイズは40,478です。
+
+#### Byte-level BPE
+
+すべてのUnicode文字をベース文字と考えると、すべての可能なベース文字が含まれるかもしれないベースボキャブラリはかなり大きくなることがあります。 [GPT-2](https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf) は、ベースボキャブラリを256バイトにする賢いトリックとしてバイトをベースボキャブラリとして使用し、すべてのベース文字がボキャブラリに含まれるようにしています。 パンクチュエーションを扱うためのいくつかの追加ルールを備えたGPT2のトークナイザは、 シンボルを必要とせずにすべてのテキストをトークン化できます。 [GPT-2](model_doc/gpt) は50,257のボキャブラリサイズを持っており、これは256バイトのベーストークン、特別なテキストの終了を示すトークン、および50,000回のマージで学習したシンボルに対応しています。
+
+### WordPiece
+
+WordPieceは、[BERT](model_doc/bert)、[DistilBERT](model_doc/distilbert)、および[Electra](model_doc/electra)で使用されるサブワードトークナイゼーションアルゴリズムです。 このアルゴリズムは、[Japanese and Korean Voice Search (Schuster et al., 2012)](https://static.googleusercontent.com/media/research.google.com/ja//pubs/archive/37842.pdf) で概説されており、BPEに非常に似ています。 WordPieceは最も頻繁なシンボルペアを選択するのではなく、トレーニングデータに追加した場合にトレーニングデータの尤度を最大化するシンボルペアを選択します。
+
+これは具体的にはどういう意味ですか?前の例を参照すると、トレーニングデータの尤度を最大化することは、そのシンボルペアの確率をその最初のシンボルに続く2番目のシンボルの確率で割ったものが、すべてのシンボルペアの中で最も大きい場合に該当するシンボルペアを見つけることに等しいです。 たとえば、"u" の後に "g" が続く場合、他のどのシンボルペアよりも "ug" の確率を "u"、"g" で割った確率が高ければ、それらのシンボルは結合されます。直感的に言えば、WordPieceは2つのシンボルを結合することによって失われるものを評価し、それがそれに値するかどうかを確認する点でBPEとはわずかに異なります。
+
+### Unigram
+
+Unigramは、[Subword Regularization: Improving Neural Network Translation Models with Multiple Subword Candidates (Kudo, 2018)](https://arxiv.org/pdf/1804.10959.pdf) で導入されたサブワードトークナイゼーションアルゴリズムです。 BPEやWordPieceとは異なり、Unigramはベースボキャブラリを多数のシンボルで初期化し、各シンボルを削減してより小さなボキャブラリを取得します。 ベースボキャブラリは、事前にトークン化されたすべての単語と最も一般的な部分文字列に対応する可能性があります。 Unigramはtransformersのモデルの直接の使用には適していませんが、[SentencePiece](#sentencepiece)と組み合わせて使用されます。
+
+各トレーニングステップで、Unigramアルゴリズムは現在のボキャブラリとユニグラム言語モデルを使用してトレーニングデータ上の損失(通常は対数尤度として定義)を定義します。その後、ボキャブラリ内の各シンボルについて、そのシンボルがボキャブラリから削除された場合に全体の損失がどれだけ増加するかを計算します。 Unigramは、損失の増加が最も低いp(通常は10%または20%)パーセントのシンボルを削除します。つまり、トレーニングデータ全体の損失に最も影響を与えない、最も損失の少ないシンボルを削除します。 このプロセスは、ボキャブラリが望ましいサイズに達するまで繰り返されます。 Unigramアルゴリズムは常にベース文字を保持するため、任意の単語をトークン化できます。
+
+Unigramはマージルールに基づいていないため(BPEとWordPieceとは対照的に)、トレーニング後の新しいテキストのトークン化にはいくつかの方法があります。例として、トレーニングされたUnigramトークナイザが持つボキャブラリが次のような場合:
+
+
+```
+["b", "g", "h", "n", "p", "s", "u", "ug", "un", "hug"],
+```
+
+`"hugs"`は、`["hug", "s"]`、`["h", "ug", "s"]`、または`["h", "u", "g", "s"]`のようにトークン化できます。では、どれを選択すべきでしょうか? Unigramは、トレーニングコーパス内の各トークンの確率を保存し、トレーニング後に各可能なトークン化の確率を計算できるようにします。このアルゴリズムは実際には最も可能性の高いトークン化を選択しますが、確率に従って可能なトークン化をサンプリングするオプションも提供します。
+
+これらの確率は、トークナイザーがトレーニングに使用する損失によって定義されます。トレーニングデータが単語 \\(x_{1}, \dots, x_{N}\\) で構成され、単語 \\(x_{i}\\) のすべての可能なトークン化のセットが \\(S(x_{i})\\) と定義される場合、全体の損失は次のように定義されます。
+
+$$\mathcal{L} = -\sum_{i=1}^{N} \log \left ( \sum_{x \in S(x_{i})} p(x) \right )$$
+
+
+
+### SentencePiece
+
+これまでに説明したすべてのトークン化アルゴリズムには同じ問題があります。それは、入力テキストが単語を区切るためにスペースを使用していると仮定しているということです。しかし、すべての言語が単語を区切るためにスペースを使用しているわけではありません。この問題を一般的に解決するための1つの方法は、言語固有の前トークナイザーを使用することです(例:[XLM](model_doc/xlm)は特定の中国語、日本語、およびタイ語の前トークナイザーを使用しています)。より一般的にこの問題を解決するために、[SentencePiece:ニューラルテキスト処理のためのシンプルで言語非依存のサブワードトークナイザーおよびデトークナイザー(Kudo et al.、2018)](https://arxiv.org/pdf/1808.06226.pdf) は、入力を生の入力ストリームとして扱い、スペースを使用する文字のセットに含めます。それからBPEまたはunigramアルゴリズムを使用して適切な語彙を構築します。
+
+たとえば、[`XLNetTokenizer`]はSentencePieceを使用しており、そのために前述の例で`"▁"`文字が語彙に含まれていました。SentencePieceを使用したデコードは非常に簡単で、すべてのトークンを単純に連結し、`"▁"`はスペースに置換されます。
+
+ライブラリ内のすべてのtransformersモデルは、SentencePieceをunigramと組み合わせて使用します。SentencePieceを使用するモデルの例には、[ALBERT](model_doc/albert)、[XLNet](model_doc/xlnet)、[Marian](model_doc/marian)、および[T5](model_doc/t5)があります。
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/torchscript.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/torchscript.md
new file mode 100644
index 0000000000000000000000000000000000000000..27d64a625c8c4299e1be68f71541966604dc65c1
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/torchscript.md
@@ -0,0 +1,177 @@
+
+
+# Export to TorchScript
+
+
+
+これはTorchScriptを使用した実験の最初であり、可変入力サイズのモデルに対するその能力をまだ探求中です。これは私たちの関心の焦点であり、今後のリリースでは、より柔軟な実装や、PythonベースのコードとコンパイルされたTorchScriptを比較するベンチマークを含む、より多くのコード例で詳細な分析を行います。
+
+
+
+[TorchScriptのドキュメント](https://pytorch.org/docs/stable/jit.html)によれば:
+
+> TorchScriptは、PyTorchコードから直列化および最適化可能なモデルを作成する方法です。
+
+TorchScriptを使用すると、効率志向のC++プログラムなど、他のプログラムでモデルを再利用できるようになります。PyTorchベースのPythonプログラム以外の環境で🤗 Transformersモデルをエクスポートして使用するためのインターフェースを提供しています。ここでは、TorchScriptを使用してモデルをエクスポートし、使用する方法を説明します。
+
+モデルをエクスポートするには、次の2つの要件があります:
+
+- `torchscript`フラグを使用したモデルのインスタンス化
+- ダミーの入力を使用したフォワードパス
+
+これらの必要条件は、以下で詳細に説明されているように、開発者が注意する必要があるいくつかのことを意味します。
+
+## TorchScript flag and tied weights
+
+`torchscript`フラグは、ほとんどの🤗 Transformers言語モデルにおいて、`Embedding`レイヤーと`Decoding`レイヤー間で重みが連結されているため必要です。
+TorchScriptでは、重みが連結されているモデルをエクスポートすることはできませんので、事前に重みを切り離して複製する必要があります。
+
+`torchscript`フラグを使用してインスタンス化されたモデルは、`Embedding`レイヤーと`Decoding`レイヤーが分離されており、そのため後でトレーニングしてはいけません。
+トレーニングは、これらの2つのレイヤーを非同期にする可能性があり、予期しない結果をもたらす可能性があります。
+
+言語モデルヘッドを持たないモデルには言及しませんが、これらのモデルには連結された重みが存在しないため、`torchscript`フラグなしで安全にエクスポートできます。
+
+## Dummy inputs and standard lengths
+
+ダミー入力はモデルのフォワードパスに使用されます。入力の値はレイヤーを通じて伝播される間、PyTorchは各テンソルに実行された異なる操作を追跡します。これらの記録された操作は、モデルの*トレース*を作成するために使用されます。
+
+トレースは入力の寸法に対して作成されます。そのため、ダミー入力の寸法に制約され、他のシーケンス長やバッチサイズでは動作しません。異なるサイズで試すと、以下のエラーが発生します:
+
+```
+`The expanded size of the tensor (3) must match the existing size (7) at non-singleton dimension 2`
+```
+
+お勧めしますのは、モデルの推論中に供給される最大の入力と同じ大きさのダミー入力サイズでモデルをトレースすることです。パディングを使用して不足値を補完することもできます。ただし、モデルがより大きな入力サイズでトレースされるため、行列の寸法も大きくなり、より多くの計算が発生します。
+
+異なるシーケンス長のモデルをエクスポートする際に、各入力に対して実行される演算の総数に注意して、パフォーマンスを密接にフォローすることをお勧めします。
+
+## Using TorchScript in Python
+
+このセクションでは、モデルの保存と読み込み、および推論にトレースを使用する方法を示します。
+
+### Saving a model
+
+TorchScriptで`BertModel`をエクスポートするには、`BertConfig`クラスから`BertModel`をインスタンス化し、それをファイル名`traced_bert.pt`でディスクに保存します:
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+
+enc = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+
+# Tokenizing input text
+text = "[CLS] Who was Jim Henson ? [SEP] Jim Henson was a puppeteer [SEP]"
+tokenized_text = enc.tokenize(text)
+
+# Masking one of the input tokens
+masked_index = 8
+tokenized_text[masked_index] = "[MASK]"
+indexed_tokens = enc.convert_tokens_to_ids(tokenized_text)
+segments_ids = [0, 0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1]
+
+# Creating a dummy input
+tokens_tensor = torch.tensor([indexed_tokens])
+segments_tensors = torch.tensor([segments_ids])
+dummy_input = [tokens_tensor, segments_tensors]
+
+# Initializing the model with the torchscript flag
+# Flag set to True even though it is not necessary as this model does not have an LM Head.
+config = BertConfig(
+ vocab_size_or_config_json_file=32000,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ torchscript=True,
+)
+
+# Instantiating the model
+model = BertModel(config)
+
+# The model needs to be in evaluation mode
+model.eval()
+
+# If you are instantiating the model with *from_pretrained* you can also easily set the TorchScript flag
+model = BertModel.from_pretrained("google-bert/bert-base-uncased", torchscript=True)
+
+# Creating the trace
+traced_model = torch.jit.trace(model, [tokens_tensor, segments_tensors])
+torch.jit.save(traced_model, "traced_bert.pt")
+```
+
+### Loading a model
+
+以前に保存した `BertModel`、`traced_bert.pt` をディスクから読み込んで、以前に初期化した `dummy_input` で使用できます。
+
+```python
+loaded_model = torch.jit.load("traced_bert.pt")
+loaded_model.eval()
+
+all_encoder_layers, pooled_output = loaded_model(*dummy_input)
+```
+
+
+### Using a traced model for inference
+
+トレースモデルを使用して推論を行うには、その `__call__` ダンダーメソッドを使用します。
+
+```python
+traced_model(tokens_tensor, segments_tensors)
+```
+
+
+## Deploy Hugging Face TorchScript models to AWS with the Neuron SDK
+
+AWSはクラウドでの低コストで高性能な機械学習推論向けに [Amazon EC2 Inf1](https://aws.amazon.com/ec2/instance-types/inf1/) インスタンスファミリーを導入しました。Inf1インスタンスはAWS Inferentiaチップによって駆動され、ディープラーニング推論ワークロードに特化したカスタムビルドのハードウェアアクセラレータです。[AWS Neuron](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/#) はInferentia用のSDKで、トランスフォーマーモデルをトレースして最適化し、Inf1に展開するためのサポートを提供します。
+
+Neuron SDK が提供するもの:
+
+1. クラウドでの推論のためにTorchScriptモデルをトレースして最適化するための、1行のコード変更で使用できる簡単なAPI。
+2. [改善されたコストパフォーマンス](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/benchmark/) のためのボックス外のパフォーマンス最適化。
+3. [PyTorch](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/bert_tutorial/tutorial_pretrained_bert.html) または [TensorFlow](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/tensorflow/huggingface_bert/huggingface_bert.html) で構築されたHugging Faceトランスフォーマーモデルへのサポート。
+
+### Implications
+
+BERT(Bidirectional Encoder Representations from Transformers)アーキテクチャやその変種([distilBERT](https://huggingface.co/docs/transformers/main/model_doc/distilbert) や [roBERTa](https://huggingface.co/docs/transformers/main/model_doc/roberta) など)に基づくトランスフォーマーモデルは、非生成タスク(抽出型質問応答、シーケンス分類、トークン分類など)において、Inf1上で最適に動作します。ただし、テキスト生成タスクも [AWS Neuron MarianMT チュートリアル](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/transformers-marianmt.html) に従ってInf1上で実行できます。Inferentiaでボックス外で変換できるモデルに関する詳細情報は、Neuronドキュメンテーションの [Model Architecture Fit](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/models/models-inferentia.html#models-inferentia) セクションにあります。
+
+### Dependencies
+
+モデルをAWS Neuronに変換するには、[Neuron SDK 環境](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/neuron-frameworks/pytorch-neuron/index.html#installation-guide) が必要で、[AWS Deep Learning AMI](https://docs.aws.amazon.com/dlami/latest/devguide/tutorial-inferentia-launching.html) に事前に構成されています。
+
+### Converting a model for AWS Neuron
+
+モデルをAWS NEURON用に変換するには、[PythonでTorchScriptを使用する](torchscript#using-torchscript-in-python) と同じコードを使用して `BertModel` をトレースします。Python APIを介してNeuron SDKのコンポーネントにアクセスするために、`torch.neuron` フレームワーク拡張をインポートします。
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+import torch.neuron
+```
+
+次の行を変更するだけで済みます。
+
+```diff
+- torch.jit.trace(model, [tokens_tensor, segments_tensors])
++ torch.neuron.trace(model, [token_tensor, segments_tensors])
+```
+
+これにより、Neuron SDKはモデルをトレースし、Inf1インスタンス向けに最適化します。
+
+AWS Neuron SDKの機能、ツール、サンプルチュートリアル、最新のアップデートについて詳しく知りたい場合は、[AWS NeuronSDK ドキュメンテーション](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/index.html) をご覧ください。
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/training.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/training.md
new file mode 100644
index 0000000000000000000000000000000000000000..9dd2369601c10a52f009dc4a790e63d14370b8d0
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/training.md
@@ -0,0 +1,434 @@
+
+
+# Fine-tune a pretrained model
+
+[[open-in-colab]]
+
+事前学習済みモデルを使用すると、計算コストを削減し、炭素排出量を減少させ、ゼロからモデルをトレーニングする必要なしに最新のモデルを使用できる利点があります。
+🤗 Transformersは、さまざまなタスクに対応した数千もの事前学習済みモデルへのアクセスを提供します。
+事前学習済みモデルを使用する場合、それを特定のタスクに合わせたデータセットでトレーニングします。これはファインチューニングとして知られ、非常に強力なトレーニング技術です。
+このチュートリアルでは、事前学習済みモデルを選択したディープラーニングフレームワークでファインチューニングする方法について説明します:
+
+* 🤗 Transformersの[`Trainer`]を使用して事前学習済みモデルをファインチューニングする。
+* TensorFlowとKerasを使用して事前学習済みモデルをファインチューニングする。
+* ネイティブのPyTorchを使用して事前学習済みモデルをファインチューニングする。
+
+
+
+## Prepare a dataset
+
+
+
+事前学習済みモデルをファインチューニングする前に、データセットをダウンロードしてトレーニング用に準備する必要があります。
+前のチュートリアルでは、トレーニングデータの処理方法を説明しましたが、これからはそれらのスキルを活かす機会があります!
+
+まず、[Yelp Reviews](https://huggingface.co/datasets/yelp_review_full)データセットを読み込んでみましょう:
+
+```python
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("yelp_review_full")
+>>> dataset["train"][100]
+{'label': 0,
+ 'text': 'My expectations for McDonalds are t rarely high. But for one to still fail so spectacularly...that takes something special!\\nThe cashier took my friends\'s order, then promptly ignored me. I had to force myself in front of a cashier who opened his register to wait on the person BEHIND me. I waited over five minutes for a gigantic order that included precisely one kid\'s meal. After watching two people who ordered after me be handed their food, I asked where mine was. The manager started yelling at the cashiers for \\"serving off their orders\\" when they didn\'t have their food. But neither cashier was anywhere near those controls, and the manager was the one serving food to customers and clearing the boards.\\nThe manager was rude when giving me my order. She didn\'t make sure that I had everything ON MY RECEIPT, and never even had the decency to apologize that I felt I was getting poor service.\\nI\'ve eaten at various McDonalds restaurants for over 30 years. I\'ve worked at more than one location. I expect bad days, bad moods, and the occasional mistake. But I have yet to have a decent experience at this store. It will remain a place I avoid unless someone in my party needs to avoid illness from low blood sugar. Perhaps I should go back to the racially biased service of Steak n Shake instead!'}
+```
+
+トークナイザがテキストを処理し、可変のシーケンス長を処理するためのパディングと切り捨て戦略を含める必要があることをご存知の通り、
+データセットを1つのステップで処理するには、🤗 Datasets の [`map`](https://huggingface.co/docs/datasets/process#map) メソッドを使用して、
+データセット全体に前処理関数を適用します:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
+
+>>> def tokenize_function(examples):
+... return tokenizer(examples["text"], padding="max_length", truncation=True)
+
+>>> tokenized_datasets = dataset.map(tokenize_function, batched=True)
+```
+
+お好みで、実行時間を短縮するためにフルデータセットの小さなサブセットを作成することができます:
+
+```py
+>>> small_train_dataset = tokenized_datasets["train"].shuffle(seed=42).select(range(1000))
+>>> small_eval_dataset = tokenized_datasets["test"].shuffle(seed=42).select(range(1000))
+```
+
+
+
+## Train
+
+この時点で、使用したいフレームワークに対応するセクションに従う必要があります。右側のサイドバーのリンクを使用して、ジャンプしたいフレームワークに移動できます。
+そして、特定のフレームワークのすべてのコンテンツを非表示にしたい場合は、そのフレームワークのブロック右上にあるボタンを使用してください!
+
+
+
+
+
+## Train with Pytorch Trainer
+
+🤗 Transformersは、🤗 Transformersモデルのトレーニングを最適化した[`Trainer`]クラスを提供し、独自のトレーニングループを手動で記述せずにトレーニングを開始しやすくしています。
+[`Trainer`] APIは、ログ記録、勾配累積、混合精度など、さまざまなトレーニングオプションと機能をサポートしています。
+
+まず、モデルをロードし、予想されるラベルの数を指定します。Yelp Review [dataset card](https://huggingface.co/datasets/yelp_review_full#data-fields)から、5つのラベルがあることがわかります:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-cased", num_labels=5)
+```
+
+
+
+一部の事前学習済みの重みが使用されず、一部の重みがランダムに初期化された警告が表示されることがあります。心配しないでください、これは完全に正常です!
+BERTモデルの事前学習済みのヘッドは破棄され、ランダムに初期化された分類ヘッドで置き換えられます。この新しいモデルヘッドをシーケンス分類タスクでファインチューニングし、事前学習モデルの知識をそれに転送します。
+
+
+
+### Training Hyperparameters
+
+次に、トレーニングオプションをアクティベートするためのすべてのハイパーパラメータと、調整できるハイパーパラメータを含む[`TrainingArguments`]クラスを作成します。
+このチュートリアルでは、デフォルトのトレーニング[ハイパーパラメータ](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments)を使用して開始できますが、最適な設定を見つけるためにこれらを実験しても構いません。
+
+トレーニングのチェックポイントを保存する場所を指定します:
+
+```python
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(output_dir="test_trainer")
+```
+
+### Evaluate
+
+[`Trainer`]はトレーニング中に自動的にモデルのパフォーマンスを評価しません。メトリクスを計算して報告する関数を[`Trainer`]に渡す必要があります。
+[🤗 Evaluate](https://huggingface.co/docs/evaluate/index)ライブラリでは、[`evaluate.load`]関数を使用して読み込むことができるシンプルな[`accuracy`](https://huggingface.co/spaces/evaluate-metric/accuracy)関数が提供されています(詳細については[こちらのクイックツアー](https://huggingface.co/docs/evaluate/a_quick_tour)を参照してください):
+
+```python
+>>> import numpy as np
+>>> import evaluate
+
+>>> metric = evaluate.load("accuracy")
+```
+
+`metric`の`~evaluate.compute`を呼び出して、予測の正確度を計算します。 `compute`に予測を渡す前に、予測をロジットに変換する必要があります(すべての🤗 Transformersモデルはロジットを返すことを覚えておいてください):
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... predictions = np.argmax(logits, axis=-1)
+... return metric.compute(predictions=predictions, references=labels)
+```
+
+評価メトリクスをファインチューニング中に監視したい場合、トレーニング引数で `eval_strategy` パラメータを指定して、各エポックの終了時に評価メトリクスを報告します:
+
+```python
+>>> from transformers import TrainingArguments, Trainer
+
+>>> training_args = TrainingArguments(output_dir="test_trainer", eval_strategy="epoch")
+```
+
+### Trainer
+
+モデル、トレーニング引数、トレーニングおよびテストデータセット、評価関数を使用して[`Trainer`]オブジェクトを作成します:
+
+```py
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... )
+```
+
+その後、[`~transformers.Trainer.train`]を呼び出してモデルを微調整します:
+
+```python
+>>> trainer.train()
+```
+
+
+
+
+
+
+
+## Kerasを使用してTensorFlowモデルをトレーニングする
+
+Keras APIを使用して🤗 TransformersモデルをTensorFlowでトレーニングすることもできます!
+
+### Loading Data from Keras
+
+🤗 TransformersモデルをKeras APIでトレーニングする場合、データセットをKerasが理解できる形式に変換する必要があります。
+データセットが小さい場合、データセット全体をNumPy配列に変換してKerasに渡すことができます。
+複雑なことをする前に、まずそれを試してみましょう。
+
+まず、データセットを読み込みます。GLUEベンチマークからCoLAデータセットを使用します
+([GLUE Banchmark](https://huggingface.co/datasets/glue))、これは単純なバイナリテキスト分類タスクです。今のところトレーニング分割のみを使用します。
+
+```py
+from datasets import load_dataset
+
+dataset = load_dataset("glue", "cola")
+dataset = dataset["train"] # 今のところトレーニング分割のみを使用します
+```
+
+次に、トークナイザをロードし、データをNumPy配列としてトークン化します。ラベルは既に`0`と`1`のリストであるため、トークン化せずに直接NumPy配列に変換できます!
+
+```python
+from transformers import AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
+tokenized_data = tokenizer(dataset["sentence"], return_tensors="np", padding=True)
+# トークナイザはBatchEncodingを返しますが、それをKeras用に辞書に変換します
+tokenized_data = dict(tokenized_data)
+
+labels = np.array(dataset["label"]) # ラベルはすでに0と1の配列です
+```
+
+最後に、モデルをロードし、[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) と [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) メソッドを実行します。
+注意点として、Transformersモデルはすべてデフォルトでタスクに関連した損失関数を持っているため、指定しなくても構いません(指定する場合を除く):
+
+```python
+from transformers import TFAutoModelForSequenceClassification
+from tensorflow.keras.optimizers import Adam
+
+# モデルをロードしてコンパイルする
+model = TFAutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-cased")
+# ファインチューニングには通常、学習率を下げると良いです
+model.compile(optimizer=Adam(3e-5)) # 損失関数の指定は不要です!
+
+model.fit(tokenized_data, labels)
+```
+
+
+
+モデルを`compile()`する際に`loss`引数を渡す必要はありません!Hugging Faceモデルは、この引数を空白のままにしておくと、タスクとモデルアーキテクチャに適した損失を自動的に選択します。
+必要に応じて自分で損失を指定してオーバーライドすることもできます!
+
+
+
+このアプローチは、小規模なデータセットには適していますが、大規模なデータセットに対しては問題になることがあります。なぜなら、トークナイズされた配列とラベルはメモリに完全に読み込まれる必要があり、またNumPyは「ジャギー」な配列を処理しないため、トークナイズされた各サンプルを全体のデータセット内で最も長いサンプルの長さにパディングする必要があります。
+これにより、配列がさらに大きくなり、すべてのパディングトークンがトレーニングを遅くする原因になります!
+
+### Loading data as a tf.data.Dataset
+
+トレーニングを遅くせずにデータを読み込むには、データを`tf.data.Dataset`として読み込むことができます。独自の`tf.data`パイプラインを作成することもできますが、これを行うための便利な方法が2つあります:
+
+- [`~TFPreTrainedModel.prepare_tf_dataset`]: これはほとんどの場合で推奨する方法です。モデル上のメソッドなので、モデルを検査してモデル入力として使用可能な列を自動的に把握し、他の列を破棄してより単純で高性能なデータセットを作成できます。
+- [`~datasets.Dataset.to_tf_dataset`]: このメソッドはより低レベルで、データセットがどのように作成されるかを正確に制御する場合に便利です。`columns`と`label_cols`を指定して、データセットに含める列を正確に指定できます。
+
+[`~TFPreTrainedModel.prepare_tf_dataset`]を使用する前に、次のコードサンプルに示すように、トークナイザの出力をデータセットに列として追加する必要があります:
+
+```py
+def tokenize_dataset(data):
+ # 返された辞書のキーはデータセットに列として追加されます
+ return tokenizer(data["text"])
+
+
+dataset = dataset.map(tokenize_dataset)
+```
+
+Hugging Faceのデータセットはデフォルトでディスクに保存されるため、これによりメモリの使用量が増えることはありません!
+列が追加されたら、データセットからバッチをストリームし、各バッチにパディングを追加できます。これにより、
+データセット全体にパディングを追加する場合と比べて、パディングトークンの数が大幅に削減されます。
+
+```python
+>>> tf_dataset = model.prepare_tf_dataset(dataset["train"], batch_size=16, shuffle=True, tokenizer=tokenizer)
+```
+
+上記のコードサンプルでは、トークナイザを`prepare_tf_dataset`に渡して、バッチを正しく読み込む際に正しくパディングできるようにする必要があります。
+データセットのすべてのサンプルが同じ長さであり、パディングが不要な場合は、この引数をスキップできます。
+パディング以外の複雑な処理を行う必要がある場合(例:マスク言語モデリングのためのトークンの破損など)、
+代わりに`collate_fn`引数を使用して、サンプルのリストをバッチに変換し、必要な前処理を適用する関数を渡すことができます。
+このアプローチを実際に使用した例については、
+[examples](https://github.com/huggingface/transformers/tree/main/examples)や
+[notebooks](https://huggingface.co/docs/transformers/notebooks)をご覧ください。
+
+`tf.data.Dataset`を作成したら、以前と同様にモデルをコンパイルし、適合させることができます:
+
+```python
+model.compile(optimizer=Adam(3e-5)) # 損失引数は不要です!
+
+model.fit(tf_dataset)
+```
+
+
+
+
+
+
+## Train in native Pytorch
+
+
+
+
+
+[`Trainer`]はトレーニングループを処理し、1行のコードでモデルをファインチューニングできるようにします。
+トレーニングループを独自に記述したいユーザーのために、🤗 TransformersモデルをネイティブのPyTorchでファインチューニングすることもできます。
+
+この時点で、ノートブックを再起動するか、以下のコードを実行してメモリを解放する必要があるかもしれません:
+
+```py
+del model
+del trainer
+torch.cuda.empty_cache()
+```
+
+1. モデルは生のテキストを入力として受け取らないため、`text` 列を削除します:
+
+```py
+>>> tokenized_datasets = tokenized_datasets.remove_columns(["text"])
+```
+
+2. `label`列を`labels`に名前を変更します。モデルは引数の名前を`labels`と期待しています:
+
+```py
+>>> tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+```
+
+3. データセットの形式をリストではなくPyTorchテンソルを返すように設定します:
+
+```py
+>>> tokenized_datasets.set_format("torch")
+```
+
+以前に示したように、ファインチューニングを高速化するためにデータセットの小さなサブセットを作成します:
+
+```py
+>>> small_train_dataset = tokenized_datasets["train"].shuffle(seed=42).select(range(1000))
+>>> small_eval_dataset = tokenized_datasets["test"].shuffle(seed=42).select(range(1000))
+```
+
+### DataLoader
+
+トレーニングデータセットとテストデータセット用の`DataLoader`を作成して、データのバッチをイテレートできるようにします:
+
+```py
+>>> from torch.utils.data import DataLoader
+
+>>> train_dataloader = DataLoader(small_train_dataset, shuffle=True, batch_size=8)
+>>> eval_dataloader = DataLoader(small_eval_dataset, batch_size=8)
+```
+
+ロードするモデルと期待されるラベルの数を指定してください:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-cased", num_labels=5)
+```
+
+### Optimizer and learning rate scheduler
+
+モデルをファインチューニングするためのオプティマイザと学習率スケジューラーを作成しましょう。
+PyTorchから[`AdamW`](https://pytorch.org/docs/stable/generated/torch.optim.AdamW.html)オプティマイザを使用します:
+
+```python
+>>> from torch.optim import AdamW
+
+>>> optimizer = AdamW(model.parameters(), lr=5e-5)
+```
+
+デフォルトの学習率スケジューラを[`Trainer`]から作成する:
+
+```py
+>>> from transformers import get_scheduler
+
+>>> num_epochs = 3
+>>> num_training_steps = num_epochs * len(train_dataloader)
+>>> lr_scheduler = get_scheduler(
+... name="linear", optimizer=optimizer, num_warmup_steps=0, num_training_steps=num_training_steps
+... )
+```
+
+最後に、GPUを利用できる場合は `device` を指定してください。それ以外の場合、CPUでのトレーニングは数時間かかる可能性があり、数分で完了することができます。
+
+```py
+>>> import torch
+
+>>> device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+>>> model.to(device)
+```
+
+
+
+クラウドGPUが利用できない場合、[Colaboratory](https://colab.research.google.com/)や[SageMaker StudioLab](https://studiolab.sagemaker.aws/)などのホストされたノートブックを使用して無料でGPUにアクセスできます。
+
+
+
+さて、トレーニングの準備が整いました! 🥳
+
+### トレーニングループ
+
+トレーニングの進捗を追跡するために、[tqdm](https://tqdm.github.io/)ライブラリを使用してトレーニングステップの数に対して進行状況バーを追加します:
+
+```py
+>>> from tqdm.auto import tqdm
+
+>>> progress_bar = tqdm(range(num_training_steps))
+
+>>> model.train()
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... outputs = model(**batch)
+... loss = outputs.loss
+... loss.backward()
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+### Evaluate
+
+[`Trainer`]に評価関数を追加したのと同様に、独自のトレーニングループを作成する際にも同様の操作を行う必要があります。
+ただし、各エポックの最後にメトリックを計算および報告する代わりに、今回は[`~evaluate.add_batch`]を使用してすべてのバッチを蓄積し、最後にメトリックを計算します。
+
+```python
+>>> import evaluate
+
+>>> metric = evaluate.load("accuracy")
+>>> model.eval()
+>>> for batch in eval_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... with torch.no_grad():
+... outputs = model(**batch)
+
+... logits = outputs.logits
+... predictions = torch.argmax(logits, dim=-1)
+... metric.add_batch(predictions=predictions, references=batch["labels"])
+
+>>> metric.compute()
+```
+
+
+
+
+
+
+## 追加リソース
+
+さらなるファインチューニングの例については、以下を参照してください:
+
+- [🤗 Transformers Examples](https://github.com/huggingface/transformers/tree/main/examples) には、PyTorchとTensorFlowで一般的なNLPタスクをトレーニングするスクリプトが含まれています。
+
+- [🤗 Transformers Notebooks](notebooks) には、特定のタスクにモデルをファインチューニングする方法に関するさまざまなノートブックが含まれています。
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/transformers_agents.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/transformers_agents.md
new file mode 100644
index 0000000000000000000000000000000000000000..572d7f290c96dc44914c01b7abf386824b3fbc89
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/transformers_agents.md
@@ -0,0 +1,282 @@
+
+
+# Transformers Agents
+
+
+
+Transformers Agentsは、いつでも変更される可能性のある実験的なAPIです。エージェントが返す結果は、APIまたは基礎となるモデルが変更される可能性があるため、異なることがあります。
+
+
+
+Transformersバージョンv4.29.0は、*ツール*と*エージェント*のコンセプトを基に構築されています。この[colab](https://colab.research.google.com/drive/1c7MHD-T1forUPGcC_jlwsIptOzpG3hSj)で試すことができます。
+
+要するに、これはtransformersの上に自然言語APIを提供するものです:私たちは一連の厳選されたツールを定義し、自然言語を解釈し、これらのツールを使用するエージェントを設計します。これは設計上拡張可能です。私たちはいくつかの関連するツールを厳選しましたが、コミュニティによって開発された任意のツールを使用するためにシステムを簡単に拡張できる方法も示します。
+
+この新しいAPIで何ができるかのいくつかの例から始めましょう。特に多モーダルなタスクに関して強力ですので、画像を生成したりテキストを読み上げたりするのに最適です。
+
+上記のテキストの上に、日本語の翻訳を提供します。
+
+
+```py
+agent.run("Caption the following image", image=image)
+```
+
+| **Input** | **Output** |
+|-----------------------------------------------------------------------------------------------------------------------------|-----------------------------------|
+| | A beaver is swimming in the water |
+
+---
+
+```py
+agent.run("Read the following text out loud", text=text)
+```
+| **Input** | **Output** |
+|-------------------------------------------------------------------------------------------------------------------------|----------------------------------------------|
+| A beaver is swimming in the water |
+
+---
+
+```py
+agent.run(
+ "In the following `document`, where will the TRRF Scientific Advisory Council Meeting take place?",
+ document=document,
+)
+```
+| **Input** | **Output** |
+|-----------------------------------------------------------------------------------------------------------------------------|----------------|
+| | ballroom foyer |
+
+## Quickstart
+
+`agent.run`を使用する前に、エージェントをインスタンス化する必要があります。エージェントは、大規模な言語モデル(LLM)です。
+OpenAIモデルとBigCode、OpenAssistantからのオープンソースの代替モデルをサポートしています。OpenAIモデルはパフォーマンスが優れていますが、OpenAIのAPIキーが必要であり、無料で使用することはできません。一方、Hugging FaceはBigCodeとOpenAssistantモデルのエンドポイントへの無料アクセスを提供しています。
+
+まず、デフォルトの依存関係をすべてインストールするために`agents`のエクストラをインストールしてください。
+
+
+```bash
+pip install transformers[agents]
+```
+
+OpenAIモデルを使用するには、`openai`の依存関係をインストールした後、`OpenAiAgent`をインスタンス化します。
+
+
+```bash
+pip install openai
+```
+
+
+```py
+from transformers import OpenAiAgent
+
+agent = OpenAiAgent(model="text-davinci-003", api_key="")
+```
+
+BigCodeまたはOpenAssistantを使用するには、まずログインしてInference APIにアクセスしてください。
+
+```py
+from huggingface_hub import login
+
+login("")
+```
+
+次に、エージェントをインスタンス化してください。
+
+```py
+from transformers import HfAgent
+
+# Starcoder
+agent = HfAgent("https://api-inference.huggingface.co/models/bigcode/starcoder")
+# StarcoderBase
+# agent = HfAgent("https://api-inference.huggingface.co/models/bigcode/starcoderbase")
+# OpenAssistant
+# agent = HfAgent(url_endpoint="https://api-inference.huggingface.co/models/OpenAssistant/oasst-sft-4-pythia-12b-epoch-3.5")
+```
+
+これは、Hugging Faceが現在無料で提供している推論APIを使用しています。このモデル(または別のモデル)の独自の推論エンドポイントをお持ちの場合は、上記のURLエンドポイントをご自分のURLエンドポイントで置き換えることができます。
+
+
+
+StarCoderとOpenAssistantは無料で利用でき、シンプルなタスクには非常に優れた性能を発揮します。ただし、より複雑なプロンプトを処理する際には、チェックポイントが十分でないことがあります。そのような場合には、現時点ではオープンソースではないものの、パフォーマンスが向上する可能性のあるOpenAIモデルを試してみることをお勧めします。
+
+
+
+これで準備が整いました!これから、あなたが利用できる2つのAPIについて詳しく説明します。
+
+### Single execution (run)
+
+単一実行メソッドは、エージェントの [`~Agent.run`] メソッドを使用する場合です。
+
+
+```py
+agent.run("Draw me a picture of rivers and lakes.")
+```
+
+
+
+
+これは、実行したいタスクに適したツール(またはツール)を自動的に選択し、適切に実行します。1つまたは複数のタスクを同じ命令で実行することができます(ただし、命令が複雑であるほど、エージェントが失敗する可能性が高くなります)。
+
+
+```py
+agent.run("Draw me a picture of the sea then transform the picture to add an island")
+```
+
+
+
+
+
+[`~Agent.run`] 操作は独立して実行できますので、異なるタスクで何度も実行することができます。
+
+注意点として、あなたの `agent` は単なる大規模な言語モデルであるため、プロンプトのわずかな変更でも完全に異なる結果が得られる可能性があります。したがって、実行したいタスクをできるだけ明確に説明することが重要です。良いプロンプトの書き方については、[こちら](custom_tools#writing-good-user-inputs) で詳しく説明しています。
+
+実行ごとに状態を保持したり、テキスト以外のオブジェクトをエージェントに渡したりする場合は、エージェントが使用する変数を指定することができます。例えば、最初の川や湖の画像を生成し、その画像に島を追加するようにモデルに指示するには、次のように行うことができます:
+
+```python
+picture = agent.run("Generate a picture of rivers and lakes.")
+updated_picture = agent.run("Transform the image in `picture` to add an island to it.", picture=picture)
+```
+
+
+
+これは、モデルがあなたのリクエストを理解できない場合や、ツールを混同する場合に役立つことがあります。例えば:
+
+```py
+agent.run("Draw me the picture of a capybara swimming in the sea")
+```
+
+ここでは、モデルは2つの方法で解釈できます:
+- `text-to-image`に海で泳ぐカピバラを生成させる
+- または、`text-to-image`でカピバラを生成し、それを海で泳がせるために`image-transformation`ツールを使用する
+
+最初のシナリオを強制したい場合は、プロンプトを引数として渡すことができます:
+
+
+```py
+agent.run("Draw me a picture of the `prompt`", prompt="a capybara swimming in the sea")
+```
+
+
+
+
+### Chat-based execution (チャット)
+
+エージェントは、[`~Agent.chat`] メソッドを使用することで、チャットベースのアプローチも可能です。
+
+
+
+```py
+agent.chat("Transform the picture so that there is a rock in there")
+```
+
+
+
+
+
+これは、指示をまたいで状態を保持したい場合に便利なアプローチで、単一の指示に比べて複雑な指示を処理するのは難しいかもしれません(その場合は [`~Agent.run`] メソッドの方が適しています)。
+
+このメソッドは、非テキスト型の引数や特定のプロンプトを渡したい場合にも使用できます。
+
+### ⚠️ Remote execution
+
+デモンストレーションの目的やすべてのセットアップで使用できるように、リリースのためにいくつかのデフォルトツール用のリモート実行ツールも作成しました。これらは [推論エンドポイント](https://huggingface.co/inference-endpoints) を使用して作成されます。
+
+これらは現在オフになっていますが、リモート実行ツールを自分で設定する方法については、[カスタムツールガイド](./custom_tools) を読むことをお勧めします。
+
+### What's happening here? What are tools, and what are agents?
+
+
+
+#### Agents
+
+ここでの「エージェント」とは、大規模な言語モデルのことであり、特定の一連のツールにアクセスできるようにプロンプトを設定しています。
+
+LLM(大規模言語モデル)は、コードの小さなサンプルを生成するのにかなり優れており、このAPIは、エージェントに特定のツールセットを使用してタスクを実行するコードの小さなサンプルを生成させることに利用しています。このプロンプトは、エージェントにタスクとツールの説明を提供することで、エージェントが使用しているツールのドキュメントにアクセスし、関連するコードを生成できるようになります。
+
+#### Tools
+
+ツールは非常に単純で、名前と説明からなる単一の関数です。それから、これらのツールの説明を使用してエージェントをプロンプトします。プロンプトを通じて、エージェントに、ツールを使用してクエリで要求されたタスクをどのように実行するかを示します。特に、ツールの期待される入力と出力を示します。
+
+これは新しいツールを使用しており、パイプラインではなくツールを使用しています。なぜなら、エージェントは非常に原子的なツールでより良いコードを生成するからです。パイプラインはよりリファクタリングされ、しばしば複数のタスクを組み合わせています。ツールは非常に単純なタスクに焦点を当てることを意図しています。
+
+#### Code-execution?!
+
+このコードは、ツールとツールと一緒に渡される入力のセットで、当社の小規模なPythonインタープリタで実行されます。すでに提供されたツールとprint関数しか呼び出すことができないため、実行できることはすでに制限されています。Hugging Faceのツールに制限されているため、安全だと考えても問題ありません。
+
+さらに、属性の検索やインポートは許可しておらず(それらは渡された入力/出力を処理するためには必要ないはずです)、最も明らかな攻撃は問題ありません(エージェントにそれらを出力するようにプロンプトする必要があります)。超安全な側に立ちたい場合は、追加の引数 return_code=True を指定して run() メソッドを実行できます。その場合、エージェントは実行するコードを返すだけで、実行するかどうかはあなた次第です。
+
+実行は、違法な操作を試みる行またはエージェントが生成したコードに通常のPythonエラーがある場合に停止します。
+
+### A curated set of tools
+
+私たちは、このようなエージェントを強化できるツールのセットを特定します。以下は、`transformers`に統合されたツールの更新されたリストです:
+
+- **ドキュメント質問応答**: 画像形式のドキュメント(PDFなど)が与えられた場合、このドキュメントに関する質問に回答します([Donut](./model_doc/donut))
+- **テキスト質問応答**: 長いテキストと質問が与えられた場合、テキスト内の質問に回答します([Flan-T5](./model_doc/flan-t5))
+- **無条件の画像キャプション**: 画像にキャプションを付けます!([BLIP](./model_doc/blip))
+- **画像質問応答**: 画像が与えられた場合、その画像に関する質問に回答します([VILT](./model_doc/vilt))
+- **画像セグメンテーション**: 画像とプロンプトが与えられた場合、そのプロンプトのセグメンテーションマスクを出力します([CLIPSeg](./model_doc/clipseg))
+- **音声からテキストへの変換**: 人の話し声のオーディオ録音が与えられた場合、その音声をテキストに転記します([Whisper](./model_doc/whisper))
+- **テキストから音声への変換**: テキストを音声に変換します([SpeechT5](./model_doc/speecht5))
+- **ゼロショットテキスト分類**: テキストとラベルのリストが与えられた場合、テキストが最も対応するラベルを識別します([BART](./model_doc/bart))
+- **テキスト要約**: 長いテキストを1つまたは数文に要約します([BART](./model_doc/bart))
+- **翻訳**: テキストを指定された言語に翻訳します([NLLB](./model_doc/nllb))
+
+これらのツールはtransformersに統合されており、手動でも使用できます。たとえば、次のように使用できます:
+
+```py
+from transformers import load_tool
+
+tool = load_tool("text-to-speech")
+audio = tool("This is a text to speech tool")
+```
+
+### Custom tools
+
+私たちは、厳選されたツールのセットを特定する一方、この実装が提供する主要な価値は、カスタムツールを迅速に作成して共有できる能力だと強く信じています。
+
+ツールのコードをHugging Face Spaceまたはモデルリポジトリにプッシュすることで、エージェントと直接連携してツールを活用できます。[`huggingface-tools` organization](https://huggingface.co/huggingface-tools)には、**transformers非依存**のいくつかのツールが追加されました:
+
+- **テキストダウンローダー**: ウェブURLからテキストをダウンロードするためのツール
+- **テキストから画像へ**: プロンプトに従って画像を生成するためのツール。安定した拡散を活用します
+- **画像変換**: 初期画像とプロンプトを指定して画像を変更するためのツール。instruct pix2pixの安定した拡散を活用します
+- **テキストからビデオへ**: プロンプトに従って小さなビデオを生成するためのツール。damo-vilabを活用します
+
+最初から使用しているテキストから画像へのツールは、[*huggingface-tools/text-to-image*](https://huggingface.co/spaces/huggingface-tools/text-to-image)にあるリモートツールです!今後も、この組織および他の組織にさらにこのようなツールをリリースし、この実装をさらに強化していきます。
+
+エージェントはデフォルトで[`huggingface-tools`](https://huggingface.co/huggingface-tools)にあるツールにアクセスできます。
+ツールの作成と共有方法、またHubに存在するカスタムツールを活用する方法についての詳細は、[次のガイド](custom_tools)で説明しています。
+
+### Code generation
+
+これまで、エージェントを使用してあなたのためにアクションを実行する方法を示しました。ただし、エージェントはコードを生成するだけで、非常に制限されたPythonインタープリタを使用して実行します。生成されたコードを異なる環境で使用したい場合、エージェントにコードを返すように指示できます。ツールの定義と正確なインポートも含めて。
+
+例えば、以下の命令:
+```python
+agent.run("Draw me a picture of rivers and lakes", return_code=True)
+```
+
+次のコードを返します
+```python
+from transformers import load_tool
+
+image_generator = load_tool("huggingface-tools/text-to-image")
+
+image = image_generator(prompt="rivers and lakes")
+```
+
+その後、自分で変更して実行できます。
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/troubleshooting.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/troubleshooting.md
new file mode 100644
index 0000000000000000000000000000000000000000..b13b5993171a0a31c9f3d9c65d70069e5909b57a
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/troubleshooting.md
@@ -0,0 +1,195 @@
+
+
+# Troubleshoot
+
+時にはエラーが発生することがありますが、私たちはここにいます!このガイドでは、私たちがよく見る最も一般的な問題と、それらを解決する方法について説明します。ただし、このガイドはすべての 🤗 Transformers の問題の包括的なコレクションではありません。問題をトラブルシューティングするための詳細なヘルプが必要な場合は、以下の方法を試してみてください:
+
+
+
+1. [フォーラム](https://discuss.huggingface.co/)で助けを求める。 [初心者向け](https://discuss.huggingface.co/c/beginners/5) または [🤗 Transformers](https://discuss.huggingface.co/c/transformers/9) など、質問を投稿できる特定のカテゴリがあります。問題が解決される可能性を最大限にするために、再現可能なコードを含む良い説明的なフォーラム投稿を書くことを確認してください!
+
+
+
+2. バグがライブラリに関連する場合は、🤗 Transformers リポジトリで [Issue](https://github.com/huggingface/transformers/issues/new/choose) を作成してください。バグを説明するためのできるだけ多くの情報を含めるように心がけ、何が問題で、どのように修正できるかをより良く理解できるようにしてください。
+
+3. より古いバージョンの 🤗 Transformers を使用している場合は、[Migration](migration) ガイドを確認してください。バージョン間で重要な変更が導入されているためです。
+
+トラブルシューティングとヘルプの詳細については、Hugging Faceコースの [第8章](https://huggingface.co/course/chapter8/1?fw=pt) を参照してください。
+
+## Firewalled environments
+
+一部のクラウド上のGPUインスタンスやイントラネットセットアップは、外部接続に対してファイアウォールで保護されているため、接続エラーが発生することがあります。スクリプトがモデルの重みやデータセットをダウンロードしようとすると、ダウンロードが途中で止まり、次のメッセージとタイムアウトエラーが表示されます:
+
+```
+ValueError: Connection error, and we cannot find the requested files in the cached path.
+Please try again or make sure your Internet connection is on.
+```
+
+
+この場合、接続エラーを回避するために[オフラインモード](installation#offline-mode)で🤗 Transformersを実行してみてください。
+
+## CUDA out of memory
+
+数百万のパラメータを持つ大規模なモデルのトレーニングは、適切なハードウェアなしでは課題です。GPUのメモリが不足するとよくあるエラーの1つは次のとおりです:
+
+以下はメモリ使用量を減らすために試すことができるいくつかの解決策です:
+
+- [`TrainingArguments`]の中で [`per_device_train_batch_size`](main_classes/trainer#transformers.TrainingArguments.per_device_train_batch_size) の値を減らす。
+- [`TrainingArguments`]の中で [`gradient_accumulation_steps`](main_classes/trainer#transformers.TrainingArguments.gradient_accumulation_steps) を使用して、全体的なバッチサイズを効果的に増やすことを試す。
+
+
+
+メモリ節約のテクニックについての詳細は、[ガイド](performance)を参照してください。
+
+
+
+## Unable to load a saved TensorFlow model
+
+TensorFlowの[model.save](https://www.tensorflow.org/tutorials/keras/save_and_load#save_the_entire_model)メソッドは、モデル全体 - アーキテクチャ、重み、トレーニング設定 - を1つのファイルに保存します。しかし、モデルファイルを再度読み込む際にエラーが発生することがあります。これは、🤗 Transformersがモデルファイル内のすべてのTensorFlow関連オブジェクトを読み込まないためです。TensorFlowモデルの保存と読み込みに関する問題を回避するために、次のことをお勧めします:
+
+- モデルの重みを`h5`ファイル拡張子で保存し、[`~TFPreTrainedModel.from_pretrained`]を使用してモデルを再読み込みする:
+
+```py
+>>> from transformers import TFPreTrainedModel
+
+>>> model.save_weights("some_folder/tf_model.h5")
+>>> model = TFPreTrainedModel.from_pretrained("some_folder")
+```
+
+- Save the model with [`~TFPretrainedModel.save_pretrained`] and load it again with [`~TFPreTrainedModel.from_pretrained`]:
+
+```py
+>>> from transformers import TFPreTrainedModel
+
+>>> model.save_pretrained("path_to/model")
+>>> model = TFPreTrainedModel.from_pretrained("path_to/model")
+```
+
+## ImportError
+
+もう一つよくあるエラーは、特に新しくリリースされたモデルの場合に遭遇することがある `ImportError` です:
+
+
+```
+ImportError: cannot import name 'ImageGPTImageProcessor' from 'transformers' (unknown location)
+```
+
+これらのエラータイプに関しては、最新バージョンの 🤗 Transformers がインストールされていることを確認して、最新のモデルにアクセスできるようにしてください:
+
+```bash
+pip install transformers --upgrade
+```
+
+## CUDA error: device-side assert triggered
+
+時々、デバイスコードでエラーが発生したという一般的な CUDA エラーに遭遇することがあります。
+
+```
+RuntimeError: CUDA error: device-side assert triggered
+```
+
+より具体的なエラーメッセージを取得するために、まずはCPU上でコードを実行してみることをお勧めします。以下の環境変数をコードの冒頭に追加して、CPUに切り替えてみてください:
+
+```py
+>>> import os
+
+>>> os.environ["CUDA_VISIBLE_DEVICES"] = ""
+```
+
+GPUからより良いトレースバックを取得する別のオプションは、次の環境変数をコードの先頭に追加することです。これにより、エラーの発生源を指すトレースバックが得られます:
+
+```py
+>>> import os
+
+>>> os.environ["CUDA_LAUNCH_BLOCKING"] = "1"
+```
+
+
+## Incorrect output when padding tokens aren't masked
+
+一部のケースでは、`input_ids`にパディングトークンが含まれている場合、出力の`hidden_state`が正しくないことがあります。デモンストレーションのために、モデルとトークナイザーをロードします。モデルの`pad_token_id`にアクセスして、その値を確認できます。一部のモデルでは`pad_token_id`が`None`になることもありますが、常に手動で設定することができます。
+
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+>>> import torch
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-uncased")
+>>> model.config.pad_token_id
+0
+```
+
+以下の例は、パディングトークンをマスクせずに出力を表示したものです:
+
+```py
+>>> input_ids = torch.tensor([[7592, 2057, 2097, 2393, 9611, 2115], [7592, 0, 0, 0, 0, 0]])
+>>> output = model(input_ids)
+>>> print(output.logits)
+tensor([[ 0.0082, -0.2307],
+ [ 0.1317, -0.1683]], grad_fn=)
+```
+
+以下は、第2のシーケンスの実際の出力です:
+
+```py
+>>> input_ids = torch.tensor([[7592]])
+>>> output = model(input_ids)
+>>> print(output.logits)
+tensor([[-0.1008, -0.4061]], grad_fn=)
+```
+
+大抵の場合、モデルには `attention_mask` を提供して、パディングトークンを無視し、このような無音のエラーを回避する必要があります。これにより、2番目のシーケンスの出力が実際の出力と一致するようになります。
+
+
+
+デフォルトでは、トークナイザは、トークナイザのデフォルトに基づいて `attention_mask` を自動で作成します。
+
+
+
+```py
+>>> attention_mask = torch.tensor([[1, 1, 1, 1, 1, 1], [1, 0, 0, 0, 0, 0]])
+>>> output = model(input_ids, attention_mask=attention_mask)
+>>> print(output.logits)
+tensor([[ 0.0082, -0.2307],
+ [-0.1008, -0.4061]], grad_fn=)
+```
+
+🤗 Transformersは、提供されるパディングトークンをマスクするために自動的に`attention_mask`を作成しません。その理由は以下の通りです:
+
+- 一部のモデルにはパディングトークンが存在しない場合があるためです。
+- 一部のユースケースでは、ユーザーがパディングトークンにアテンションを向けることを望む場合があるためです。
+
+## ValueError: Unrecognized configuration class XYZ for this kind of AutoModel
+
+一般的に、事前学習済みモデルのインスタンスをロードするためには[`AutoModel`]クラスを使用することをお勧めします。このクラスは、設定に基づいて与えられたチェックポイントから正しいアーキテクチャを自動的に推測およびロードできます。モデルをロードする際にこの`ValueError`が表示される場合、Autoクラスは与えられたチェックポイントの設定から、ロードしようとしているモデルの種類へのマッピングを見つけることができなかったことを意味します。最も一般的には、特定のタスクをサポートしないチェックポイントがある場合にこのエラーが発生します。
+例えば、質問応答のためのGPT2が存在しない場合、次の例でこのエラーが表示されます:
+
+上記のテキストを日本語に翻訳し、Markdownファイルとしてフォーマットしました。
+
+
+```py
+>>> from transformers import AutoProcessor, AutoModelForQuestionAnswering
+
+>>> processor = AutoProcessor.from_pretrained("openai-community/gpt2-medium")
+>>> model = AutoModelForQuestionAnswering.from_pretrained("openai-community/gpt2-medium")
+ValueError: Unrecognized configuration class for this kind of AutoModel: AutoModelForQuestionAnswering.
+Model type should be one of AlbertConfig, BartConfig, BertConfig, BigBirdConfig, BigBirdPegasusConfig, BloomConfig, ...
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/_config.py b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/_config.py
new file mode 100644
index 0000000000000000000000000000000000000000..ab61af6ef9e86028ae075e01fb244ae4226f387b
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/_config.py
@@ -0,0 +1,14 @@
+# docstyle-ignore
+INSTALL_CONTENT = """
+# Transformers 설치 방법
+! pip install transformers datasets evaluate accelerate
+# 마지막 릴리스 대신 소스에서 설치하려면, 위 명령을 주석으로 바꾸고 아래 명령을 해제하세요.
+# ! pip install git+https://github.com/huggingface/transformers.git
+"""
+
+notebook_first_cells = [{"type": "code", "content": INSTALL_CONTENT}]
+black_avoid_patterns = {
+ "{processor_class}": "FakeProcessorClass",
+ "{model_class}": "FakeModelClass",
+ "{object_class}": "FakeObjectClass",
+}
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/_toctree.yml b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..6257bca6c953070cdfae220931b7f5f1a1fae693
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/_toctree.yml
@@ -0,0 +1,790 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers
+ - local: quicktour
+ title: 둘러보기
+ - local: installation
+ title: 설치방법
+ title: 시작하기
+- sections:
+ - local: pipeline_tutorial
+ title: Pipeline으로 추론하기
+ - local: autoclass_tutorial
+ title: AutoClass로 사전 학습된 인스턴스 로드하기
+ - local: preprocessing
+ title: 데이터 전처리하기
+ - local: training
+ title: 사전 학습된 모델 미세 조정하기
+ - local: run_scripts
+ title: 스크립트로 학습하기
+ - local: accelerate
+ title: 🤗 Accelerate로 분산 학습 구성하기
+ - local: peft
+ title: 🤗 PEFT로 어댑터 로드 및 학습하기
+ - local: model_sharing
+ title: 만든 모델 공유하기
+ - local: transformers_agents
+ title: 에이전트
+ - local: llm_tutorial
+ title: 대규모 언어 모델로 생성하기
+ - local: conversations
+ title: Transformers로 채팅하기
+ title: 튜토리얼
+- sections:
+ - isExpanded: false
+ sections:
+ - local: tasks/sequence_classification
+ title: 텍스트 분류
+ - local: tasks/token_classification
+ title: 토큰 분류
+ - local: tasks/question_answering
+ title: 질의 응답(Question Answering)
+ - local: tasks/language_modeling
+ title: 인과적 언어 모델링(Causal language modeling)
+ - local: tasks/masked_language_modeling
+ title: 마스킹된 언어 모델링(Masked language modeling)
+ - local: tasks/translation
+ title: 번역
+ - local: tasks/summarization
+ title: 요약
+ - local: tasks/multiple_choice
+ title: 객관식 문제(Multiple Choice)
+ title: 자연어처리
+ - isExpanded: false
+ sections:
+ - local: tasks/audio_classification
+ title: 오디오 분류
+ - local: tasks/asr
+ title: 자동 음성 인식
+ title: 오디오
+ - isExpanded: false
+ sections:
+ - local: tasks/image_classification
+ title: 이미지 분류
+ - local: tasks/semantic_segmentation
+ title: 의미적 분할(Semantic segmentation)
+ - local: tasks/video_classification
+ title: 영상 분류
+ - local: tasks/object_detection
+ title: 객체 탐지
+ - local: tasks/zero_shot_object_detection
+ title: 제로샷(zero-shot) 객체 탐지
+ - local: tasks/zero_shot_image_classification
+ title: 제로샷(zero-shot) 이미지 분류
+ - local: tasks/monocular_depth_estimation
+ title: 단일 영상 기반 깊이 추정
+ - local: tasks/image_to_image
+ title: Image-to-Image
+ - local: tasks/image_feature_extraction
+ title: 이미지 특징 추출
+ - local: tasks/mask_generation
+ title: 마스크 생성
+ - local: tasks/knowledge_distillation_for_image_classification
+ title: 컴퓨터 비전(이미지 분류)를 위한 지식 증류(knowledge distillation)
+ title: 컴퓨터 비전
+ - isExpanded: false
+ sections:
+ - local: tasks/image_captioning
+ title: 이미지 캡셔닝
+ - local: tasks/document_question_answering
+ title: 문서 질의 응답(Document Question Answering)
+ - local: tasks/visual_question_answering
+ title: 시각적 질의응답 (Visual Question Answering)
+ - local: in_translation
+ title: (번역중) Text to speech
+ title: 멀티모달
+ - isExpanded: false
+ sections:
+ - local: generation_strategies
+ title: 텍스트 생성 전략 사용자 정의
+ title: 생성
+ - isExpanded: false
+ sections:
+ - local: tasks/idefics
+ title: IDEFICS를 이용한 이미지 작업
+ - local: tasks/prompting
+ title: 대규모 언어 모델 프롬프팅 가이드
+ title: 프롬프팅
+ title: 태스크 가이드
+- sections:
+ - local: fast_tokenizers
+ title: 🤗 Tokenizers 라이브러리에서 토크나이저 사용하기
+ - local: multilingual
+ title: 다국어 모델 추론하기
+ - local: create_a_model
+ title: 모델별 API 사용하기
+ - local: custom_models
+ title: 사용자 정의 모델 공유하기
+ - local: chat_templating
+ title: 챗봇 템플릿 익히기
+ - local: trainer
+ title: Trainer 사용하기
+ - local: sagemaker
+ title: Amazon SageMaker에서 학습 실행하기
+ - local: serialization
+ title: ONNX로 내보내기
+ - local: tflite
+ title: TFLite로 내보내기
+ - local: torchscript
+ title: TorchScript로 내보내기
+ - local: in_translation
+ title: (번역중) Notebooks with examples
+ - local: community
+ title: 커뮤니티 리소스
+ - local: troubleshooting
+ title: 문제 해결
+ - local: gguf
+ title: GGUF 파일들과의 상호 운용성
+ - local: modular_transformers
+ title: transformers에서의 모듈성
+ title: (번역중) 개발자 가이드
+- sections:
+ - local: in_translation
+ title: (번역중) Getting started
+ - local: quantization/bitsandbytes
+ title: bitsandbytes
+ - local: quantization/gptq
+ title: GPTQ
+ - local: quantization/awq
+ title: AWQ
+ - local: in_translation
+ title: (번역중) AQLM
+ - local: in_translation
+ title: (번역중) VPTQ
+ - local: quantization/quanto
+ title: Quanto
+ - local: quantization/eetq
+ title: EETQ
+ - local: in_translation
+ title: (번역중) HQQ
+ - local: in_translation
+ title: (번역중) Optimum
+ - local: in_translation
+ title: (번역중) Contribute new quantization method
+ title: (번역중) 경량화 메소드
+- sections:
+ - local: performance
+ title: 성능 및 확장성
+ - local: in_translation
+ title: (번역중) Quantization
+ - local: llm_optims
+ title: LLM 추론 최적화
+ - sections:
+ - local: in_translation
+ title: (번역중) Methods and tools for efficient training on a single GPU
+ - local: perf_train_gpu_many
+ title: 다중 GPU에서 훈련 진행하기
+ - local: deepspeed
+ title: DeepSpeed
+ - local: fsdp
+ title: 완전 분할 데이터 병렬 처리
+ - local: perf_train_cpu
+ title: CPU에서 훈련
+ - local: perf_train_cpu_many
+ title: 다중 CPU에서 훈련하기
+ - local: perf_train_tpu_tf
+ title: TensorFlow로 TPU에서 훈련하기
+ - local: perf_train_special
+ title: Apple 실리콘에서 PyTorch 학습
+ - local: perf_hardware
+ title: 훈련용 사용자 맞춤형 하드웨어
+ - local: hpo_train
+ title: Trainer API를 사용한 하이퍼파라미터 탐색
+ title: (번역중) 효율적인 학습 기술들
+ - sections:
+ - local: perf_infer_cpu
+ title: CPU로 추론하기
+ - local: perf_infer_gpu_one
+ title: 하나의 GPU를 활용한 추론
+ title: 추론 최적화하기
+ - local: big_models
+ title: 대형 모델을 인스턴스화
+ - local: debugging
+ title: 디버깅
+ - local: tf_xla
+ title: TensorFlow 모델을 위한 XLA 통합
+ - local: in_translation
+ title: (번역중) Optimize inference using `torch.compile()`
+ title: (번역중) 성능 및 확장성
+- sections:
+ - local: contributing
+ title: 🤗 Transformers에 기여하는 방법
+ - local: add_new_model
+ title: 🤗 Transformers에 새로운 모델을 추가하는 방법
+ - local: add_new_pipeline
+ title: 어떻게 🤗 Transformers에 파이프라인을 추가하나요?
+ - local: testing
+ title: 테스트
+ - local: pr_checks
+ title: Pull Request에 대한 검사
+ title: 기여하기
+- sections:
+ - local: philosophy
+ title: 이념과 목표
+ - local: in_translation
+ title: (번역중) Glossary
+ - local: task_summary
+ title: 🤗 Transformers로 할 수 있는 작업
+ - local: tasks_explained
+ title: 🤗 Transformers로 작업을 해결하는 방법
+ - local: model_summary
+ title: Transformer 모델군
+ - local: tokenizer_summary
+ title: 토크나이저 요약
+ - local: attention
+ title: 어텐션 매커니즘
+ - local: pad_truncation
+ title: 패딩과 잘라내기
+ - local: bertology
+ title: BERTology
+ - local: perplexity
+ title: 고정 길이 모델의 펄플렉서티(Perplexity)
+ - local: pipeline_webserver
+ title: 추론 웹 서버를 위한 파이프라인
+ - local: model_memory_anatomy
+ title: 모델 학습 해부하기
+ - local: llm_tutorial_optimization
+ title: LLM을 최대한 활용하기
+ title: (번역중) 개념 가이드
+- sections:
+ - sections:
+ - local: main_classes/agent
+ title: 에이전트와 도구
+ - local: model_doc/auto
+ title: 자동 클래스
+ - local: in_translation
+ title: (번역중) Backbones
+ - local: main_classes/callback
+ title: 콜백
+ - local: main_classes/configuration
+ title: 구성
+ - local: main_classes/data_collator
+ title: 데이터 콜레이터
+ - local: main_classes/keras_callbacks
+ title: 케라스 콜백
+ - local: main_classes/logging
+ title: 로깅
+ - local: main_classes/model
+ title: Models
+ - local: main_classes/text_generation
+ title: 텍스트 생성
+ - local: main_classes/onnx
+ title: ONNX
+ - local: in_translation
+ title: (번역중) Optimization
+ - local: in_translation
+ title: 모델 출력
+ - local: main_classes/output
+ title: (번역중) Pipelines
+ - local: in_translation
+ title: (번역중) Processors
+ - local: main_classes/quantization
+ title: 양자화
+ - local: in_translation
+ title: (번역중) Tokenizer
+ - local: main_classes/trainer
+ title: Trainer
+ - local: deepspeed
+ title: DeepSpeed
+ - local: main_classes/executorch
+ title: ExecuTorch
+ - local: main_classes/feature_extractor
+ title: 특성 추출기
+ - local: in_translation
+ title: (번역중) Image Processor
+ title: (번역중) 메인 클래스
+ - sections:
+ - isExpanded: false
+ sections:
+ - local: in_translation
+ title: (번역중) ALBERT
+ - local: model_doc/bart
+ title: BART
+ - local: model_doc/barthez
+ title: BARThez
+ - local: model_doc/bartpho
+ title: BARTpho
+ - local: model_doc/bert
+ title: BERT
+ - local: in_translation
+ title: (번역중) BertGeneration
+ - local: model_doc/bert-japanese
+ title: 일본어 Bert
+ - local: model_doc/bertweet
+ title: Bertweet
+ - local: in_translation
+ title: (번역중) BigBird
+ - local: in_translation
+ title: (번역중) BigBirdPegasus
+ - local: model_doc/biogpt
+ title: BioGpt
+ - local: in_translation
+ title: (번역중) Blenderbot
+ - local: in_translation
+ title: (번역중) Blenderbot Small
+ - local: in_translation
+ title: (번역중) BLOOM
+ - local: in_translation
+ title: (번역중) BORT
+ - local: in_translation
+ title: (번역중) ByT5
+ - local: in_translation
+ title: (번역중) CamemBERT
+ - local: in_translation
+ title: (번역중) CANINE
+ - local: in_translation
+ title: (번역중) CodeGen
+ - local: model_doc/cohere
+ title: Cohere
+ - local: model_doc/convbert
+ title: ConvBERT
+ - local: in_translation
+ title: (번역중) CPM
+ - local: in_translation
+ title: (번역중) CPMANT
+ - local: in_translation
+ title: (번역중) CTRL
+ - local: model_doc/dbrx
+ title: DBRX
+ - local: model_doc/deberta
+ title: DeBERTa
+ - local: model_doc/deberta-v2
+ title: DeBERTa-v2
+ - local: in_translation
+ title: (번역중) DialoGPT
+ - local: in_translation
+ title: (번역중) DistilBERT
+ - local: in_translation
+ title: (번역중) DPR
+ - local: in_translation
+ title: (번역중) ELECTRA
+ - local: model_doc/encoder-decoder
+ title: 인코더 디코더 모델
+ - local: in_translation
+ title: (번역중) ERNIE
+ - local: in_translation
+ title: (번역중) ErnieM
+ - local: model_doc/esm
+ title: ESM
+ - local: in_translation
+ title: (번역중) FLAN-T5
+ - local: in_translation
+ title: (번역중) FLAN-UL2
+ - local: in_translation
+ title: (번역중) FlauBERT
+ - local: in_translation
+ title: (번역중) FNet
+ - local: in_translation
+ title: (번역중) FSMT
+ - local: in_translation
+ title: (번역중) Funnel Transformer
+ - local: model_doc/gemma
+ title: Gemma
+ - local: model_doc/gemma2
+ title: Gemma2
+ - local: model_doc/openai-gpt
+ title: GPT
+ - local: in_translation
+ title: (번역중) GPT Neo
+ - local: in_translation
+ title: (번역중) GPT NeoX
+ - local: model_doc/gpt_neox_japanese
+ title: GPT NeoX Japanese
+ - local: in_translation
+ title: (번역중) GPT-J
+ - local: in_translation
+ title: (번역중) GPT2
+ - local: in_translation
+ title: (번역중) GPTBigCode
+ - local: in_translation
+ title: (번역중) GPTSAN Japanese
+ - local: in_translation
+ title: (번역중) GPTSw3
+ - local: in_translation
+ title: (번역중) HerBERT
+ - local: in_translation
+ title: (번역중) I-BERT
+ - local: in_translation
+ title: (번역중) Jukebox
+ - local: in_translation
+ title: (번역중) LED
+ - local: model_doc/llama
+ title: LLaMA
+ - local: model_doc/llama2
+ title: LLaMA2
+ - local: model_doc/llama3
+ title: LLaMA3
+ - local: in_translation
+ title: (번역중) Longformer
+ - local: in_translation
+ title: (번역중) LongT5
+ - local: in_translation
+ title: (번역중) LUKE
+ - local: in_translation
+ title: (번역중) M2M100
+ - local: model_doc/mamba
+ title: Mamba
+ - local: model_doc/mamba2
+ title: Mamba2
+ - local: model_doc/marian
+ title: MarianMT
+ - local: in_translation
+ title: (번역중) MarkupLM
+ - local: in_translation
+ title: (번역중) MBart and MBart-50
+ - local: in_translation
+ title: (번역중) MEGA
+ - local: in_translation
+ title: (번역중) MegatronBERT
+ - local: in_translation
+ title: (번역중) MegatronGPT2
+ - local: model_doc/mistral
+ title: Mistral
+ - local: in_translation
+ title: (번역중) mLUKE
+ - local: in_translation
+ title: (번역중) MobileBERT
+ - local: in_translation
+ title: (번역중) MPNet
+ - local: in_translation
+ title: (번역중) MT5
+ - local: in_translation
+ title: (번역중) MVP
+ - local: in_translation
+ title: (번역중) NEZHA
+ - local: in_translation
+ title: (번역중) NLLB
+ - local: in_translation
+ title: (번역중) NLLB-MoE
+ - local: in_translation
+ title: (번역중) Nyströmformer
+ - local: in_translation
+ title: (번역중) Open-Llama
+ - local: in_translation
+ title: (번역중) OPT
+ - local: in_translation
+ title: (번역중) Pegasus
+ - local: in_translation
+ title: (번역중) PEGASUS-X
+ - local: in_translation
+ title: (번역중) PhoBERT
+ - local: in_translation
+ title: (번역중) PLBart
+ - local: in_translation
+ title: (번역중) ProphetNet
+ - local: in_translation
+ title: (번역중) QDQBert
+ - local: model_doc/rag
+ title: RAG(검색 증강 생성)
+ - local: in_translation
+ title: (번역중) REALM
+ - local: in_translation
+ title: (번역중) Reformer
+ - local: in_translation
+ title: (번역중) RemBERT
+ - local: in_translation
+ title: (번역중) RetriBERT
+ - local: in_translation
+ title: (번역중) RoBERTa
+ - local: in_translation
+ title: (번역중) RoBERTa-PreLayerNorm
+ - local: in_translation
+ title: (번역중) RoCBert
+ - local: in_translation
+ title: (번역중) RoFormer
+ - local: in_translation
+ title: (번역중) Splinter
+ - local: in_translation
+ title: (번역중) SqueezeBERT
+ - local: in_translation
+ title: (번역중) SwitchTransformers
+ - local: in_translation
+ title: (번역중) T5
+ - local: in_translation
+ title: (번역중) T5v1.1
+ - local: in_translation
+ title: (번역중) TAPEX
+ - local: in_translation
+ title: (번역중) Transformer XL
+ - local: in_translation
+ title: (번역중) UL2
+ - local: in_translation
+ title: (번역중) X-MOD
+ - local: in_translation
+ title: (번역중) XGLM
+ - local: in_translation
+ title: (번역중) XLM
+ - local: in_translation
+ title: (번역중) XLM-ProphetNet
+ - local: in_translation
+ title: (번역중) XLM-RoBERTa
+ - local: in_translation
+ title: (번역중) XLM-RoBERTa-XL
+ - local: in_translation
+ title: (번역중) XLM-V
+ - local: in_translation
+ title: (번역중) XLNet
+ - local: in_translation
+ title: (번역중) YOSO
+ title: (번역중) 텍스트 모델
+ - isExpanded: false
+ sections:
+ - local: in_translation
+ title: (번역중) BEiT
+ - local: in_translation
+ title: (번역중) BiT
+ - local: in_translation
+ title: (번역중) Conditional DETR
+ - local: in_translation
+ title: (번역중) ConvNeXT
+ - local: in_translation
+ title: (번역중) ConvNeXTV2
+ - local: in_translation
+ title: (번역중) CvT
+ - local: in_translation
+ title: (번역중) Deformable DETR
+ - local: in_translation
+ title: (번역중) DeiT
+ - local: in_translation
+ title: (번역중) DETA
+ - local: in_translation
+ title: (번역중) DETR
+ - local: in_translation
+ title: (번역중) DiNAT
+ - local: in_translation
+ title: (번역중) DiT
+ - local: in_translation
+ title: (번역중) DPT
+ - local: in_translation
+ title: (번역중) EfficientFormer
+ - local: in_translation
+ title: (번역중) EfficientNet
+ - local: in_translation
+ title: (번역중) FocalNet
+ - local: in_translation
+ title: (번역중) GLPN
+ - local: in_translation
+ title: (번역중) ImageGPT
+ - local: in_translation
+ title: (번역중) LeViT
+ - local: in_translation
+ title: (번역중) Mask2Former
+ - local: in_translation
+ title: (번역중) MaskFormer
+ - local: in_translation
+ title: (번역중) MobileNetV1
+ - local: in_translation
+ title: (번역중) MobileNetV2
+ - local: in_translation
+ title: (번역중) MobileViT
+ - local: in_translation
+ title: (번역중) NAT
+ - local: in_translation
+ title: (번역중) PoolFormer
+ - local: in_translation
+ title: (번역중) RegNet
+ - local: in_translation
+ title: (번역중) ResNet
+ - local: in_translation
+ title: (번역중) SegFormer
+ - local: model_doc/swin
+ title: Swin Transformer
+ - local: model_doc/swinv2
+ title: Swin Transformer V2
+ - local: model_doc/swin2sr
+ title: Swin2SR
+ - local: in_translation
+ title: (번역중) Table Transformer
+ - local: in_translation
+ title: (번역중) TimeSformer
+ - local: in_translation
+ title: (번역중) UperNet
+ - local: in_translation
+ title: (번역중) VAN
+ - local: in_translation
+ title: (번역중) VideoMAE
+ - local: in_translation
+ title: Vision Transformer (ViT)
+ - local: model_doc/vit
+ title: (번역중) ViT Hybrid
+ - local: in_translation
+ title: (번역중) ViTMAE
+ - local: in_translation
+ title: (번역중) ViTMSN
+ - local: in_translation
+ title: (번역중) YOLOS
+ title: (번역중) 비전 모델
+ - isExpanded: false
+ sections:
+ - local: in_translation
+ title: (번역중) Audio Spectrogram Transformer
+ - local: in_translation
+ title: (번역중) CLAP
+ - local: in_translation
+ title: (번역중) Hubert
+ - local: in_translation
+ title: (번역중) MCTCT
+ - local: in_translation
+ title: (번역중) SEW
+ - local: in_translation
+ title: (번역중) SEW-D
+ - local: in_translation
+ title: (번역중) Speech2Text
+ - local: in_translation
+ title: (번역중) Speech2Text2
+ - local: in_translation
+ title: (번역중) SpeechT5
+ - local: in_translation
+ title: (번역중) UniSpeech
+ - local: in_translation
+ title: (번역중) UniSpeech-SAT
+ - local: in_translation
+ title: (번역중) Wav2Vec2
+ - local: in_translation
+ title: (번역중) Wav2Vec2-Conformer
+ - local: in_translation
+ title: (번역중) Wav2Vec2Phoneme
+ - local: in_translation
+ title: (번역중) WavLM
+ - local: model_doc/whisper
+ title: Whisper
+ - local: in_translation
+ title: (번역중) XLS-R
+ - local: in_translation
+ title: (번역중) XLSR-Wav2Vec2
+ title: (번역중) 오디오 모델
+ - isExpanded: false
+ sections:
+ - local: model_doc/timesformer
+ title: TimeSformer
+ - local: in_translation
+ title: (번역중) VideoMAE
+ - local: model_doc/vivit
+ title: ViViT
+ title: (번역중) 비디오 모델
+ - isExpanded: false
+ sections:
+ - local: in_translation
+ title: (번역중) ALIGN
+ - local: model_doc/altclip
+ title: AltCLIP
+ - local: model_doc/blip-2
+ title: BLIP-2
+ - local: model_doc/blip
+ title: BLIP
+ - local: in_translation
+ title: (번역중) BridgeTower
+ - local: model_doc/chameleon
+ title: Chameleon
+ - local: in_translation
+ title: (번역중) Chinese-CLIP
+ - local: model_doc/clip
+ title: CLIP
+ - local: in_translation
+ title: (번역중) CLIPSeg
+ - local: in_translation
+ title: (번역중) Data2Vec
+ - local: in_translation
+ title: (번역중) DePlot
+ - local: in_translation
+ title: (번역중) Donut
+ - local: in_translation
+ title: (번역중) FLAVA
+ - local: in_translation
+ title: (번역중) GIT
+ - local: in_translation
+ title: (번역중) GroupViT
+ - local: in_translation
+ title: (번역중) LayoutLM
+ - local: in_translation
+ title: (번역중) LayoutLMV2
+ - local: in_translation
+ title: (번역중) LayoutLMV3
+ - local: in_translation
+ title: (번역중) LayoutXLM
+ - local: in_translation
+ title: (번역중) LiLT
+ - local: in_translation
+ title: (번역중) LXMERT
+ - local: in_translation
+ title: (번역중) MatCha
+ - local: in_translation
+ title: (번역중) MGP-STR
+ - local: in_translation
+ title: (번역중) OneFormer
+ - local: in_translation
+ title: (번역중) OWL-ViT
+ - local: model_doc/paligemma
+ title: PaliGemma
+ - local: in_translation
+ title: (번역중) Perceiver
+ - local: in_translation
+ title: (번역중) Pix2Struct
+ - local: in_translation
+ title: (번역중) Segment Anything
+ - local: in_translation
+ title: (번역중) Speech Encoder Decoder Models
+ - local: in_translation
+ title: (번역중) TAPAS
+ - local: in_translation
+ title: (번역중) TrOCR
+ - local: in_translation
+ title: (번역중) TVLT
+ - local: in_translation
+ title: (번역중) ViLT
+ - local: in_translation
+ title: (번역중) Vision Encoder Decoder Models
+ - local: in_translation
+ title: (번역중) Vision Text Dual Encoder
+ - local: in_translation
+ title: (번역중) VisualBERT
+ - local: in_translation
+ title: (번역중) X-CLIP
+ title: (번역중) 멀티모달 모델
+ - isExpanded: false
+ sections:
+ - local: in_translation
+ title: (번역중) Decision Transformer
+ - local: model_doc/trajectory_transformer
+ title: 궤적 트랜스포머
+ title: (번역중) 강화학습 모델
+ - isExpanded: false
+ sections:
+ - local: model_doc/autoformer
+ title: Autoformer
+ - local: model_doc/informer
+ title: Informer
+ - local: model_doc/patchtsmixer
+ title: PatchTSMixer
+ - local: model_doc/patchtst
+ title: PatchTST
+ - local: model_doc/time_series_transformer
+ title: 시계열 트랜스포머
+ title: 시계열 모델
+ - isExpanded: false
+ sections:
+ - local: model_doc/graphormer
+ title: Graphormer
+ title: 그래프 모델
+ title: (번역중) 모델
+ - sections:
+ - local: internal/modeling_utils
+ title: 사용자 정의 레이어 및 유틸리티
+ - local: internal/pipelines_utils
+ title: 파이프라인을 위한 유틸리티
+ - local: internal/tokenization_utils
+ title: 토크나이저를 위한 유틸리티
+ - local: internal/trainer_utils
+ title: Trainer를 위한 유틸리티
+ - local: internal/generation_utils
+ title: 생성을 위한 유틸리티
+ - local: internal/image_processing_utils
+ title: 이미지 프로세서를 위한 유틸리티
+ - local: internal/audio_utils
+ title: 오디오 처리를 위한 유틸리티
+ - local: internal/file_utils
+ title: 일반 유틸리티
+ - local: internal/time_series_utils
+ title: 시계열을 위한 유틸리티
+ title: (번역중) Internal Helpers
+ title: (번역중) API
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/accelerate.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/accelerate.md
new file mode 100644
index 0000000000000000000000000000000000000000..0ef8957de3ac20d38326624d60e7cd1fd349197b
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/accelerate.md
@@ -0,0 +1,136 @@
+
+
+# 🤗 Accelerate를 활용한 분산 학습[[distributed-training-with-accelerate]]
+
+모델이 커지면서 병렬 처리는 제한된 하드웨어에서 더 큰 모델을 훈련하고 훈련 속도를 몇 배로 가속화하기 위한 전략으로 등장했습니다. Hugging Face에서는 사용자가 하나의 머신에 여러 개의 GPU를 사용하든 여러 머신에 여러 개의 GPU를 사용하든 모든 유형의 분산 설정에서 🤗 Transformers 모델을 쉽게 훈련할 수 있도록 돕기 위해 [🤗 Accelerate](https://huggingface.co/docs/accelerate) 라이브러리를 만들었습니다. 이 튜토리얼에서는 분산 환경에서 훈련할 수 있도록 기본 PyTorch 훈련 루프를 커스터마이즈하는 방법을 알아봅시다.
+
+## 설정[[setup]]
+
+🤗 Accelerate 설치 시작하기:
+
+```bash
+pip install accelerate
+```
+
+그 다음, [`~accelerate.Accelerator`] 객체를 불러오고 생성합니다. [`~accelerate.Accelerator`]는 자동으로 분산 설정 유형을 감지하고 훈련에 필요한 모든 구성 요소를 초기화합니다. 장치에 모델을 명시적으로 배치할 필요는 없습니다.
+
+```py
+>>> from accelerate import Accelerator
+
+>>> accelerator = Accelerator()
+```
+
+## 가속화를 위한 준비[[prepare-to-accelerate]]
+
+다음 단계는 관련된 모든 훈련 객체를 [`~accelerate.Accelerator.prepare`] 메소드에 전달하는 것입니다. 여기에는 훈련 및 평가 데이터로더, 모델 및 옵티마이저가 포함됩니다:
+
+```py
+>>> train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
+... train_dataloader, eval_dataloader, model, optimizer
+... )
+```
+
+## 백워드(Backward)[[backward]]
+
+마지막으로 훈련 루프의 일반적인 `loss.backward()`를 🤗 Accelerate의 [`~accelerate.Accelerator.backward`] 메소드로 대체하기만 하면 됩니다:
+
+```py
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... outputs = model(**batch)
+... loss = outputs.loss
+... accelerator.backward(loss)
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+다음 코드에서 볼 수 있듯이, 훈련 루프에 코드 네 줄만 추가하면 분산 학습을 활성화할 수 있습니다!
+
+```diff
++ from accelerate import Accelerator
+ from transformers import AdamW, AutoModelForSequenceClassification, get_scheduler
+
++ accelerator = Accelerator()
+
+ model = AutoModelForSequenceClassification.from_pretrained(checkpoint, num_labels=2)
+ optimizer = AdamW(model.parameters(), lr=3e-5)
+
+- device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+- model.to(device)
+
++ train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
++ train_dataloader, eval_dataloader, model, optimizer
++ )
+
+ num_epochs = 3
+ num_training_steps = num_epochs * len(train_dataloader)
+ lr_scheduler = get_scheduler(
+ "linear",
+ optimizer=optimizer,
+ num_warmup_steps=0,
+ num_training_steps=num_training_steps
+ )
+
+ progress_bar = tqdm(range(num_training_steps))
+
+ model.train()
+ for epoch in range(num_epochs):
+ for batch in train_dataloader:
+- batch = {k: v.to(device) for k, v in batch.items()}
+ outputs = model(**batch)
+ loss = outputs.loss
+- loss.backward()
++ accelerator.backward(loss)
+
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ progress_bar.update(1)
+```
+
+## 학습[[train]]
+
+관련 코드를 추가한 후에는 스크립트나 Colaboratory와 같은 노트북에서 훈련을 시작하세요.
+
+### 스크립트로 학습하기[[train-with-a-script]]
+
+스크립트에서 훈련을 실행하는 경우, 다음 명령을 실행하여 구성 파일을 생성하고 저장합니다:
+
+```bash
+accelerate config
+```
+
+Then launch your training with:
+
+```bash
+accelerate launch train.py
+```
+
+### 노트북으로 학습하기[[train-with-a-notebook]]
+
+Collaboratory의 TPU를 사용하려는 경우, 노트북에서도 🤗 Accelerate를 실행할 수 있습니다. 훈련을 담당하는 모든 코드를 함수로 감싸서 [`~accelerate.notebook_launcher`]에 전달하세요:
+
+```py
+>>> from accelerate import notebook_launcher
+
+>>> notebook_launcher(training_function)
+```
+
+🤗 Accelerate 및 다양한 기능에 대한 자세한 내용은 [documentation](https://huggingface.co/docs/accelerate)를 참조하세요.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/add_new_model.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/add_new_model.md
new file mode 100644
index 0000000000000000000000000000000000000000..d5834777d31eefbb00188d11ce1c115557793eab
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/add_new_model.md
@@ -0,0 +1,626 @@
+
+
+# Hugging Face Transformers를 추가하는 방법은 무엇인가요? [[how-to-add-a-model-to-transformers]]
+
+Hugging Face Transformers 라이브러리는 커뮤니티 기여자들 덕분에 새로운 모델을 제공할 수 있는 경우가 많습니다. 하지만 이는 도전적인 프로젝트이며 Hugging Face Transformers 라이브러리와 구현할 모델에 대한 깊은 이해가 필요합니다. Hugging Face에서는 더 많은 커뮤니티 멤버가 모델을 적극적으로 추가할 수 있도록 지원하고자 하며, 이 가이드를 통해 PyTorch 모델을 추가하는 과정을 안내하고 있습니다 (PyTorch가 설치되어 있는지 확인해주세요).
+
+이 과정을 진행하면 다음과 같은 내용을 이해하게 됩니다:
+
+- 오픈 소스의 모범 사례에 대한 통찰력을 얻습니다.
+- 가장 인기 있는 딥러닝 라이브러리의 설계 원칙을 이해합니다.
+- 대규모 모델을 효율적으로 테스트하는 방법을 배웁니다.
+- `black`, `ruff`, `make fix-copies`와 같은 Python 유틸리티를 통합하여 깔끔하고 가독성 있는 코드를 작성하는 방법을 배웁니다.
+
+Hugging Face 팀은 항상 도움을 줄 준비가 되어 있으므로 혼자가 아니라는 점을 기억하세요. 🤗 ❤️
+
+시작에 앞서 🤗 Transformers에 원하는 모델을 추가하기 위해 [New model addition](https://github.com/huggingface/transformers/issues/new?assignees=&labels=New+model&template=new-model-addition.yml) 이슈를 열어야 합니다. 특정 모델을 기여하는 데 특별히 까다로운 기준을 가지지 않는 경우 [New model label](https://github.com/huggingface/transformers/labels/New%20model)을 필터링하여 요청되지 않은 모델이 있는지 확인하고 작업할 수 있습니다.
+
+새로운 모델 요청을 열었다면 첫 번째 단계는 🤗 Transformers에 익숙해지는 것입니다!
+
+## 🤗 Transformers의 전반적인 개요 [[general-overview-of-transformers]]
+
+먼저 🤗 Transformers에 대한 전반적인 개요를 파악해야 합니다. 🤗 Transformers는 매우 주관적인 라이브러리이기 때문에 해당 라이브러리의 철학이나 설계 선택 사항에 동의하지 않을 수도 있습니다. 그러나 우리의 경험상 라이브러리의 기본적인 설계 선택과 철학은 🤗 Transformers의 규모를 효율적으로 확장하면서 유지 보수 비용을 합리적인 수준으로 유지하는 것입니다.
+
+[라이브러리의 철학에 대한 문서](philosophy)를 읽는 것이 라이브러리를 더 잘 이해하는 좋은 시작점입니다. 모든 모델에 적용하려는 몇 가지 작업 방식에 대한 선택 사항이 있습니다:
+
+- 일반적으로 추상화보다는 구성을 선호합니다.
+- 코드를 복제하는 것이 항상 나쁜 것은 아닙니다. 코드의 가독성이나 접근성을 크게 향상시킨다면 복제하는 것은 좋습니다.
+- 모델 파일은 가능한 한 독립적으로 유지되어야 합니다. 따라서 특정 모델의 코드를 읽을 때 해당 `modeling_....py` 파일만 확인하면 됩니다.
+
+우리는 라이브러리의 코드가 제품을 제공하는 수단뿐만 아니라 개선하고자 하는 제품이라고도 생각합니다. 따라서 모델을 추가할 때, 사용자는 모델을 사용할 사람뿐만 아니라 코드를 읽고 이해하고 필요한 경우 조정할 수 있는 모든 사람까지도 포함한다는 점을 기억해야 합니다.
+
+이를 염두에 두고 일반적인 라이브러리 설계에 대해 조금 더 자세히 알아보겠습니다.
+
+### 모델 개요 [[overview-of-models]]
+
+모델을 성공적으로 추가하려면 모델과 해당 구성인 [`PreTrainedModel`] 및 [`PretrainedConfig`] 간의 상호작용을 이해하는 것이 중요합니다. 예를 들어, 🤗 Transformers에 추가하려는 모델을 `BrandNewBert`라고 부르겠습니다.
+
+다음을 살펴보겠습니다:
+
+
+
+보다시피, 🤗 Transformers에서는 상속을 사용하지만 추상화 수준을 최소한으로 유지합니다. 라이브러리의 어떤 모델에서도 두 수준 이상의 추상화가 존재하지 않습니다. `BrandNewBertModel`은 `BrandNewBertPreTrainedModel`에서 상속받고, 이 클래스는 [`PreTrainedModel`]에서 상속받습니다. 이로써 새로운 모델은 [`PreTrainedModel`]에만 의존하도록 하려고 합니다. 모든 새로운 모델에 자동으로 제공되는 중요한 기능은 [`~PreTrainedModel.from_pretrained`] 및 [`~PreTrainedModel.save_pretrained`]입니다. 이러한 기능 외에도 `BrandNewBertModel.forward`와 같은 다른 중요한 기능은 새로운 `modeling_brand_new_bert.py` 스크립트에서 완전히 정의되어야 합니다. 또한 `BrandNewBertForMaskedLM`과 같은 특정 헤드 레이어를 가진 모델은 `BrandNewBertModel`을 상속받지 않고 forward pass에서 호출할 수 있는 `BrandNewBertModel`을 사용하여 추상화 수준을 낮게 유지합니다. 모든 새로운 모델은 `BrandNewBertConfig`라는 구성 클래스를 필요로 합니다. 이 구성은 항상 [`PreTrainedModel`]의 속성으로 저장되며, 따라서 `BrandNewBertPreTrainedModel`을 상속받는 모든 클래스에서 `config` 속성을 통해 액세스할 수 있습니다:
+
+```python
+model = BrandNewBertModel.from_pretrained("brandy/brand_new_bert")
+model.config # model has access to its config
+```
+
+모델과 마찬가지로 구성은 [`PretrainedConfig`]에서 기본 직렬화 및 역직렬화 기능을 상속받습니다. 구성과 모델은 항상 *pytorch_model.bin* 파일과 *config.json* 파일로 각각 별도로 직렬화됩니다. [`~PreTrainedModel.save_pretrained`]를 호출하면 자동으로 [`~PretrainedConfig.save_pretrained`]도 호출되므로 모델과 구성이 모두 저장됩니다.
+
+
+### 코드 스타일 [[code-style]]
+
+새로운 모델을 작성할 때, Transformers는 주관적인 라이브러리이며 몇 가지 독특한 코딩 스타일이 있습니다:
+
+1. 모델의 forward pass는 모델 파일에 완전히 작성되어야 합니다. 라이브러리의 다른 모델에서 블록을 재사용하려면 코드를 복사하여 위에 `# Copied from` 주석과 함께 붙여넣으면 됩니다 (예: [여기](https://github.com/huggingface/transformers/blob/v4.17.0/src/transformers/models/roberta/modeling_roberta.py#L160)를 참조하세요).
+2. 코드는 완전히 이해하기 쉬워야 합니다. 변수 이름을 명확하게 지정하고 약어를 사용하지 않는 것이 좋습니다. 예를 들어, `act`보다는 `activation`을 선호합니다. 한 글자 변수 이름은 루프의 인덱스인 경우를 제외하고 권장되지 않습니다.
+3. 더 일반적으로, 짧은 마법 같은 코드보다는 길고 명시적인 코드를 선호합니다.
+4. PyTorch에서 `nn.Sequential`을 하위 클래스로 만들지 말고 `nn.Module`을 하위 클래스로 만들고 forward pass를 작성하여 다른 사람이 코드를 빠르게 디버그할 수 있도록 합니다. print 문이나 중단점을 추가할 수 있습니다.
+5. 함수 시그니처에는 타입 주석을 사용해야 합니다. 그 외에는 타입 주석보다 변수 이름이 훨씬 읽기 쉽고 이해하기 쉽습니다.
+
+### 토크나이저 개요 [[overview-of-tokenizers]]
+
+아직 준비되지 않았습니다 :-( 이 섹션은 곧 추가될 예정입니다!
+
+## 🤗 Transformers에 모델 추가하는 단계별 방법 [[stepbystep-recipe-to-add-a-model-to-transformers]]
+
+각자 모델을 이식하는 방법에 대한 선호가 다르기 때문에 다른 기여자들이 Hugging Face에 모델을 이식하는 방법에 대한 요약을 살펴보는 것이 매우 유용할 수 있습니다. 다음은 모델을 이식하는 방법에 대한 커뮤니티 블로그 게시물 목록입니다:
+
+1. [GPT2 모델 이식하기](https://medium.com/huggingface/from-tensorflow-to-pytorch-265f40ef2a28) - [Thomas](https://huggingface.co/thomwolf)
+2. [WMT19 MT 모델 이식하기](https://huggingface.co/blog/porting-fsmt) - [Stas](https://huggingface.co/stas)
+
+경험상 모델을 추가할 때 주의해야 할 가장 중요한 사항은 다음과 같습니다:
+
+- 같은 일을 반복하지 마세요! 새로운 🤗 Transformers 모델을 위해 추가할 코드의 대부분은 이미 🤗 Transformers 어딘가에 존재합니다. 이미 존재하는 복사할 수 있는 유사한 모델과 토크나이저를 찾는데 시간을 투자하세요. [grep](https://www.gnu.org/software/grep/)와 [rg](https://github.com/BurntSushi/ripgrep)를 참고하세요. 모델의 토크나이저가 한 모델을 기반으로 하고 모델링 코드가 다른 모델을 기반으로 하는 경우가 존재할 수도 있습니다. 예를 들어 FSMT의 모델링 코드는 BART를 기반으로 하고 FSMT의 토크나이저 코드는 XLM을 기반으로 합니다.
+- 이것은 과학적인 도전보다는 공학적인 도전입니다. 논문의 모델의 모든 이론적 측면을 이해하려는 것보다 효율적인 디버깅 환경을 만드는 데 더 많은 시간을 소비해야 합니다.
+- 막힐 때 도움을 요청하세요! 모델은 🤗 Transformers의 핵심 구성 요소이므로 Hugging Face의 우리는 당신이 모델을 추가하는 각 단계에서 기꺼이 도움을 줄 준비가 되어 있습니다. 진전이 없다고 느끼면 주저하지 말고 도움을 요청하세요.
+
+다음에서는 모델을 🤗 Transformers로 이식하는 데 가장 유용한 일반적인 절차를 제공하려고 노력합니다.
+
+다음 목록은 모델을 추가하는 데 수행해야 할 모든 작업의 요약이며 To-Do 목록으로 사용할 수 있습니다:
+
+☐ (선택 사항) BrandNewBert의 이론적 측면 이해
+☐ Hugging Face 개발 환경 준비
+☐ 원본 리포지토리의 디버깅 환경 설정
+☐ 원본 리포지토리와 체크포인트를 사용하여 `forward()` pass가 성공적으로 실행되는 스크립트 작성
+☐ 🤗 Transformers에 모델 스켈레톤 성공적으로 추가
+☐ 원본 체크포인트를 🤗 Transformers 체크포인트로 성공적으로 변환
+☐ 🤗 Transformers에서 원본 체크포인트와 동일한 출력을 내주는 `forward()` pass 성공적으로 실행
+☐ 🤗 Transformers에서 모델 테스트 완료
+☐ 🤗 Transformers에 토크나이저 성공적으로 추가
+☐ 종단 간 통합 테스트 실행
+☐ 문서 작성 완료
+☐ 모델 가중치를 허브에 업로드
+☐ Pull request 제출
+☐ (선택 사항) 데모 노트북 추가
+
+우선, 일반적으로는 `BrandNewBert`의 이론적인 이해로 시작하는 것을 권장합니다. 그러나 이론적 측면을 직접 이해하는 대신 *직접 해보면서* 모델의 이론적 측면을 이해하는 것을 선호하는 경우 바로 `BrandNewBert` 코드 베이스로 빠져드는 것도 괜찮습니다. 이 옵션은 엔지니어링 기술이 이론적 기술보다 더 뛰어난 경우, `BrandNewBert`의 논문을 이해하는 데 어려움이 있는 경우, 또는 과학적인 논문을 읽는 것보다 프로그래밍에 훨씬 더 흥미 있는 경우에 더 적합할 수 있습니다.
+
+### 1. (선택 사항) BrandNewBert의 이론적 측면 [[1-optional-theoretical-aspects-of-brandnewbert]]
+
+만약 그런 서술적인 작업이 존재한다면, *BrandNewBert*의 논문을 읽어보는 시간을 가져야 합니다. 이해하기 어려운 섹션이 많을 수 있습니다. 그렇더라도 걱정하지 마세요! 목표는 논문의 깊은 이론적 이해가 아니라 *BrandNewBert*를 🤗 Transformers에서 효과적으로 재구현하기 위해 필요한 정보를 추출하는 것입니다. 이를 위해 이론적 측면에 너무 많은 시간을 투자할 필요는 없지만 다음과 같은 실제적인 측면에 집중해야 합니다:
+
+- *BrandNewBert*는 어떤 유형의 모델인가요? BERT와 유사한 인코더 모델인가요? GPT2와 유사한 디코더 모델인가요? BART와 유사한 인코더-디코더 모델인가요? 이들 간의 차이점에 익숙하지 않은 경우[model_summary](model_summary)를 참조하세요.
+- *BrandNewBert*의 응용 분야는 무엇인가요? 텍스트 분류인가요? 텍스트 생성인가요? 요약과 같은 Seq2Seq 작업인가요?
+- *brand_new_bert*와 BERT/GPT-2/BART의 차이점은 무엇인가요?
+- *brand_new_bert*와 가장 유사한 [🤗 Transformers 모델](https://huggingface.co/transformers/#contents)은 무엇인가요?
+- 어떤 종류의 토크나이저가 사용되나요? Sentencepiece 토크나이저인가요? Word piece 토크나이저인가요? BERT 또는 BART에 사용되는 동일한 토크나이저인가요?
+
+모델의 아키텍처에 대해 충분히 이해했다는 생각이 든 후, 궁금한 사항이 있으면 Hugging Face 팀에 문의하십시오. 이는 모델의 아키텍처, 어텐션 레이어 등에 관한 질문을 포함할 수 있습니다. Hugging Face의 유지 관리자들은 보통 코드를 검토하는 것에 대해 매우 기뻐하므로 당신을 돕는 일을 매우 환영할 것입니다!
+
+### 2. 개발 환경 설정 [[2-next-prepare-your-environment]]
+
+1. 저장소 페이지에서 "Fork" 버튼을 클릭하여 저장소의 사본을 GitHub 사용자 계정으로 만듭니다.
+
+2. `transformers` fork를 로컬 디스크에 클론하고 베이스 저장소를 원격 저장소로 추가합니다:
+
+```bash
+git clone https://github.com/[your Github handle]/transformers.git
+cd transformers
+git remote add upstream https://github.com/huggingface/transformers.git
+```
+
+3. 개발 환경을 설정합니다. 다음 명령을 실행하여 개발 환경을 설정할 수 있습니다:
+
+```bash
+python -m venv .env
+source .env/bin/activate
+pip install -e ".[dev]"
+```
+
+각 운영 체제에 따라 Transformers의 선택적 의존성이 개수가 증가하면 이 명령이 실패할 수 있습니다. 그런 경우에는 작업 중인 딥 러닝 프레임워크 (PyTorch, TensorFlow 및/또는 Flax)을 설치한 후, 다음 명령을 수행하면 됩니다:
+
+```bash
+pip install -e ".[quality]"
+```
+
+대부분의 경우에는 이것으로 충분합니다. 그런 다음 상위 디렉토리로 돌아갑니다.
+
+```bash
+cd ..
+```
+
+4. Transformers에 *brand_new_bert*의 PyTorch 버전을 추가하는 것을 권장합니다. PyTorch를 설치하려면 다음 링크의 지침을 따르십시오: https://pytorch.org/get-started/locally/.
+
+**참고:** CUDA를 설치할 필요는 없습니다. 새로운 모델이 CPU에서 작동하도록 만드는 것으로 충분합니다.
+
+5. *brand_new_bert*를 이식하기 위해서는 해당 원본 저장소에 접근할 수 있어야 합니다:
+
+```bash
+git clone https://github.com/org_that_created_brand_new_bert_org/brand_new_bert.git
+cd brand_new_bert
+pip install -e .
+```
+
+이제 *brand_new_bert*를 🤗 Transformers로 이식하기 위한 개발 환경을 설정하였습니다.
+
+### 3.-4. 원본 저장소에서 사전 훈련된 체크포인트 실행하기 [[3.-4.-run-a-pretrained-checkpoint-using-the-original-repository]]
+
+먼저, 원본 *brand_new_bert* 저장소에서 작업을 시작합니다. 원본 구현은 보통 "연구용"으로 많이 사용됩니다. 즉, 문서화가 부족하고 코드가 이해하기 어려울 수 있습니다. 그러나 이것이 바로 *brand_new_bert*를 다시 구현하려는 동기가 되어야 합니다. Hugging Face에서의 주요 목표 중 하나는 **거인의 어깨 위에 서는 것**이며, 이는 여기에서 쉽게 해석되어 동작하는 모델을 가져와서 가능한 한 **접근 가능하고 사용자 친화적이며 아름답게** 만드는 것입니다. 이것은 🤗 Transformers에서 모델을 다시 구현하는 가장 중요한 동기입니다 - 새로운 복잡한 NLP 기술을 **모두에게** 접근 가능하게 만드는 것을 목표로 합니다.
+
+따라서 원본 저장소에 대해 자세히 살펴보는 것으로 시작해야 합니다.
+
+원본 저장소에서 공식 사전 훈련된 모델을 성공적으로 실행하는 것은 종종 **가장 어려운** 단계입니다. 우리의 경험에 따르면, 원본 코드 베이스에 익숙해지는 데 시간을 투자하는 것이 매우 중요합니다. 다음을 파악해야 합니다:
+
+- 사전 훈련된 가중치를 어디서 찾을 수 있는지?
+- 사전 훈련된 가중치를 해당 모델에로드하는 방법은?
+- 모델과 독립적으로 토크나이저를 실행하는 방법은?
+- 간단한 forward pass에 필요한 클래스와 함수를 파악하기 위해 forward pass를 한 번 추적해 보세요. 일반적으로 해당 함수들만 다시 구현하면 됩니다.
+- 모델의 중요한 구성 요소를 찾을 수 있어야 합니다. 모델 클래스는 어디에 있나요? 모델 하위 클래스(*EncoderModel*, *DecoderModel* 등)가 있나요? self-attention 레이어는 어디에 있나요? self-attention, cross-attention 등 여러 가지 다른 어텐션 레이어가 있나요?
+- 원본 환경에서 모델을 디버그할 수 있는 방법은 무엇인가요? *print* 문을 추가해야 하나요? *ipdb*와 같은 대화식 디버거를 사용할 수 있나요? PyCharm과 같은 효율적인 IDE를 사용해 모델을 디버그할 수 있나요?
+
+원본 저장소에서 코드를 이식하는 작업을 시작하기 전에 원본 저장소에서 코드를 **효율적으로** 디버그할 수 있어야 합니다! 또한, 오픈 소스 라이브러리로 작업하고 있다는 것을 기억해야 합니다. 따라서 원본 저장소에서 issue를 열거나 pull request를 열기를 주저하지 마십시오. 이 저장소의 유지 관리자들은 누군가가 자신들의 코드를 살펴본다는 것에 대해 매우 기뻐할 것입니다!
+
+현재 시점에서, 원래 모델을 디버깅하기 위해 어떤 디버깅 환경과 전략을 선호하는지는 당신에게 달렸습니다. 우리는 고가의 GPU 환경을 구축하는 것은 비추천합니다. 대신, 원래 저장소로 들어가서 작업을 시작할 때와 🤗 Transformers 모델의 구현을 시작할 때에도 CPU에서 작업하는 것이 좋습니다. 모델이 이미 🤗 Transformers로 성공적으로 이식되었을 때에만 모델이 GPU에서도 예상대로 작동하는지 확인해야합니다.
+
+일반적으로, 원래 모델을 실행하기 위한 두 가지 가능한 디버깅 환경이 있습니다.
+
+- [Jupyter 노트북](https://jupyter.org/) / [Google Colab](https://colab.research.google.com/notebooks/intro.ipynb)
+- 로컬 Python 스크립트
+
+Jupyter 노트북의 장점은 셀 단위로 실행할 수 있다는 것입니다. 이는 논리적인 구성 요소를 더 잘 분리하고 중간 결과를 저장할 수 있으므로 디버깅 사이클이 더 빨라질 수 있습니다. 또한, 노트북은 다른 기여자와 쉽게 공유할 수 있으므로 Hugging Face 팀의 도움을 요청하려는 경우 매우 유용할 수 있습니다. Jupyter 노트북에 익숙하다면 이를 사용하는 것을 강력히 추천합니다.
+
+Jupyter 노트북의 단점은 사용에 익숙하지 않은 경우 새로운 프로그래밍 환경에 적응하는 데 시간을 할애해야 하며, `ipdb`와 같은 알려진 디버깅 도구를 더 이상 사용할 수 없을 수도 있다는 것입니다.
+
+각 코드 베이스에 대해 좋은 첫 번째 단계는 항상 **작은** 사전 훈련된 체크포인트를 로드하고 더미 정수 벡터 입력을 사용하여 단일 forward pass를 재현하는 것입니다. 이와 같은 스크립트는 다음과 같을 수 있습니다(의사 코드로 작성):
+
+```python
+model = BrandNewBertModel.load_pretrained_checkpoint("/path/to/checkpoint/")
+input_ids = [0, 4, 5, 2, 3, 7, 9] # vector of input ids
+original_output = model.predict(input_ids)
+```
+
+다음으로, 디버깅 전략에 대해 일반적으로 다음과 같은 몇 가지 선택지가 있습니다:
+
+- 원본 모델을 많은 작은 테스트 가능한 구성 요소로 분해하고 각각에 대해 forward pass를 실행하여 검증합니다.
+- 원본 모델을 원본 *tokenizer*과 원본 *model*로만 분해하고 해당 부분에 대해 forward pass를 실행한 후 검증을 위해 중간 출력(print 문 또는 중단점)을 사용합니다.
+
+다시 말하지만, 어떤 전략을 선택할지는 당신에게 달려 있습니다. 원본 코드 베이스에 따라 하나 또는 다른 전략이 유리할 수 있습니다.
+
+원본 코드 베이스를 모델의 작은 하위 구성 요소로 분해할 수 있는지 여부, 예를 들어 원본 코드 베이스가 즉시 실행 모드에서 간단히 실행될 수 있는 경우, 그런 경우에는 그 노력이 가치가 있다는 것이 일반적입니다. 초기에 더 어려운 방법을 선택하는 것에는 몇 가지 중요한 장점이 있습니다.
+
+- 원본 모델을 🤗 Transformers 구현과 비교할 때 각 구성 요소가 일치하는지 자동으로 확인할 수 있습니다. 즉, 시각적인 비교(print 문을 통한 비교가 아닌) 대신 🤗 Transformers 구현과 그에 대응하는 원본 구성 요소가 일치하는지 확인할 수 있습니다.
+- 전체 모델을 모듈별로, 즉 작은 구성 요소로 분해함으로써 모델을 이식하는 큰 문제를 단순히 개별 구성 요소를 이식하는 작은 문제로 분해할 수 있으므로 작업을 더 잘 구조화할 수 있습니다.
+- 모델을 논리적으로 의미 있는 구성 요소로 분리하는 것은 모델의 설계에 대한 더 나은 개요를 얻고 모델을 더 잘 이해하는 데 도움이 됩니다.
+- 이러한 구성 요소별 테스트를 통해 코드를 변경하면서 회귀가 발생하지 않도록 보장할 수 있습니다.
+
+[Lysandre의 ELECTRA 통합 검사](https://gist.github.com/LysandreJik/db4c948f6b4483960de5cbac598ad4ed)는 이를 수행하는 좋은 예제입니다.
+
+그러나 원본 코드 베이스가 매우 복잡하거나 중간 구성 요소를 컴파일된 모드에서 실행하는 것만 허용하는 경우, 모델을 테스트 가능한 작은 하위 구성 요소로 분해하는 것이 시간이 많이 소요되거나 불가능할 수도 있습니다. [T5의 MeshTensorFlow](https://github.com/tensorflow/mesh/tree/master/mesh_tensorflow) 라이브러리는 매우 복잡하며 모델을 하위 구성 요소로 분해하는 간단한 방법을 제공하지 않습니다. 이러한 라이브러리의 경우, 보통 print 문을 통해 확인합니다.
+
+어떤 전략을 선택하더라도 권장되는 절차는 동일합니다. 먼저 시작 레이어를 디버그하고 마지막 레이어를 마지막에 디버그하는 것이 좋습니다.
+
+다음 순서로 각 레이어의 출력을 검색하는 것이 좋습니다:
+
+1. 모델에 전달된 입력 ID 가져오기
+2. 워드 임베딩 가져오기
+3. 첫 번째 Transformer 레이어의 입력 가져오기
+4. 첫 번째 Transformer 레이어의 출력 가져오기
+5. 다음 n-1개의 Transformer 레이어의 출력 가져오기
+6. BrandNewBert 모델의 출력 가져오기
+
+입력 ID는 정수 배열로 구성되며, 예를 들어 `input_ids = [0, 4, 4, 3, 2, 4, 1, 7, 19]`와 같을 수 있습니다.
+
+다음 레이어의 출력은 종종 다차원 실수 배열로 구성되며, 다음과 같이 나타낼 수 있습니다:
+
+```
+[[
+ [-0.1465, -0.6501, 0.1993, ..., 0.1451, 0.3430, 0.6024],
+ [-0.4417, -0.5920, 0.3450, ..., -0.3062, 0.6182, 0.7132],
+ [-0.5009, -0.7122, 0.4548, ..., -0.3662, 0.6091, 0.7648],
+ ...,
+ [-0.5613, -0.6332, 0.4324, ..., -0.3792, 0.7372, 0.9288],
+ [-0.5416, -0.6345, 0.4180, ..., -0.3564, 0.6992, 0.9191],
+ [-0.5334, -0.6403, 0.4271, ..., -0.3339, 0.6533, 0.8694]]],
+```
+
+🤗 Transformers에 추가되는 모든 모델은 통합 테스트를 통과해야 합니다. 즉, 원본 모델과 🤗 Transformers의 재구현 버전이 0.001의 정밀도로 정확히 동일한 출력을 내야 합니다! 동일한 모델이 다른 라이브러리에서 작성되었을 때 라이브러리 프레임워크에 따라 약간 다른 출력을 얻는 것은 정상이므로 1e-3(0.001)의 오차는 허용합니다. 거의 동일한 출력을 내는 것만으로는 충분하지 않으며, 완벽히 일치하는 수준이어야 합니다. 따라서 🤗 Transformers 버전의 중간 출력을 *brand_new_bert*의 원래 구현의 중간 출력과 여러 번 비교해야 합니다. 이 경우 원본 저장소의 **효율적인** 디버깅 환경이 절대적으로 중요합니다. 디버깅 환경을 가능한 한 효율적으로 만드는 몇 가지 조언을 제시합니다.
+
+- 중간 결과를 디버그하는 가장 좋은 방법을 찾으세요. 원본 저장소가 PyTorch로 작성되었다면 원본 모델을 더 작은 하위 구성 요소로 분해하여 중간 값을 검색하는 긴 스크립트를 작성하는 것에 시간을 투자할 가치가 있습니다. 원본 저장소가 Tensorflow 1로 작성되었다면 [tf.print](https://www.tensorflow.org/api_docs/python/tf/print)와 같은 Tensorflow 출력 작업을 사용하여 중간 값을 출력해야 할 수도 있습니다. 원본 저장소가 Jax로 작성되었다면 forward pass를 실행할 때 모델이 **jit 되지 않도록** 해야 합니다. 예를 들어 [이 링크](https://github.com/google/jax/issues/196)를 확인해 보세요.
+- 사용 가능한 가장 작은 사전 훈련된 체크포인트를 사용하세요. 체크포인트가 작을수록 디버그 사이클이 더 빨라집니다. 전반적으로 forward pass에 10초 이상이 걸리는 경우 효율적이지 않습니다. 매우 큰 체크포인트만 사용할 수 있는 경우, 새 환경에서 임의로 초기화된 가중치로 더미 모델을 만들고 해당 가중치를 🤗 Transformers 버전과 비교하기 위해 저장하는 것이 더 의미가 있을 수 있습니다.
+- 디버깅 설정에서 가장 쉽게 forward pass를 호출하는 방법을 사용하세요. 원본 저장소에서 **단일** forward pass만 호출하는 함수를 찾는 것이 이상적입니다. 이 함수는 일반적으로 `predict`, `evaluate`, `forward`, `__call__`과 같이 호출됩니다. `autoregressive_sample`과 같은 텍스트 생성에서 `forward`를 여러 번 호출하여 텍스트를 생성하는 등의 작업을 수행하는 함수를 디버그하고 싶지 않을 것입니다.
+- 토큰화 과정을 모델의 *forward* pass와 분리하려고 노력하세요. 원본 저장소에서 입력 문자열을 입력해야 하는 예제가 있는 경우, 입력 문자열이 입력 ID로 변경되는 순간을 찾아서 시작하세요. 이 경우 직접 ID를 입력할 수 있도록 작은 스크립트를 작성하거나 원본 코드를 수정해야 할 수도 있습니다.
+- 디버깅 설정에서 모델이 훈련 모드가 아니라는 것을 확인하세요. 훈련 모드에서는 모델의 여러 드롭아웃 레이어 때문에 무작위 출력이 생성될 수 있습니다. 디버깅 환경에서 forward pass가 **결정론적**이도록 해야 합니다. 또는 동일한 프레임워크에 있는 경우 *transformers.utils.set_seed*를 사용하세요.
+
+다음 섹션에서는 *brand_new_bert*에 대해 이 작업을 수행하는 데 더 구체적인 세부 사항/팁을 제공합니다.
+
+### 5.-14. 🤗 Transformers에 BrandNewBert를 이식하기 [[5.-14.-port-brandnewbert-to-transformers]]
+
+이제, 마침내 🤗 Transformers에 새로운 코드를 추가할 수 있습니다. 🤗 Transformers 포크의 클론으로 이동하세요:
+
+```bash
+cd transformers
+```
+
+다음과 같이 이미 존재하는 모델의 모델 아키텍처와 정확히 일치하는 모델을 추가하는 특별한 경우에는 [이 섹션](#write-a-conversion-script)에 설명된대로 변환 스크립트만 추가하면 됩니다. 이 경우에는 이미 존재하는 모델의 전체 모델 아키텍처를 그대로 재사용할 수 있습니다.
+
+그렇지 않으면 새 모델 생성을 시작하겠습니다. 다음 스크립트를 사용하여 다음에서 시작하는 모델을 추가하는 것이 좋습니다.
+기존 모델:
+
+```bash
+transformers-cli add-new-model-like
+```
+
+모델의 기본 정보를 입력하는 설문지가 표시됩니다.
+
+**huggingface/transformers 메인 저장소에 Pull Request 열기**
+
+자동으로 생성된 코드를 수정하기 전에, 지금은 "작업 진행 중 (WIP)" 풀 리퀘스트를 열기 위한 시기입니다. 예를 들어, 🤗 Transformers에 "*brand_new_bert* 추가"라는 제목의 "[WIP] Add *brand_new_bert*" 풀 리퀘스트를 엽니다. 이렇게 하면 당신과 Hugging Face 팀이 🤗 Transformers에 모델을 통합하는 작업을 함께할 수 있습니다.
+
+다음을 수행해야 합니다:
+
+1. 메인 브랜치에서 작업을 잘 설명하는 이름으로 브랜치 생성
+
+```bash
+git checkout -b add_brand_new_bert
+```
+
+2. 자동으로 생성된 코드 커밋
+
+```bash
+git add .
+git commit
+```
+
+3. 현재 메인을 가져오고 리베이스
+
+```bash
+git fetch upstream
+git rebase upstream/main
+```
+
+4. 변경 사항을 계정에 푸시
+
+```bash
+git push -u origin a-descriptive-name-for-my-changes
+```
+
+5. 만족스럽다면, GitHub에서 자신의 포크한 웹 페이지로 이동합니다. "Pull request"를 클릭합니다. Hugging Face 팀의 일부 멤버의 GitHub 핸들을 리뷰어로 추가하여 Hugging Face 팀이 앞으로의 변경 사항에 대해 알림을 받을 수 있도록 합니다.
+
+6. GitHub 풀 리퀘스트 웹 페이지 오른쪽에 있는 "Convert to draft"를 클릭하여 PR을 초안으로 변경합니다.
+
+다음으로, 어떤 진전을 이루었다면 작업을 커밋하고 계정에 푸시하여 풀 리퀘스트에 표시되도록 해야 합니다. 또한, 다음과 같이 현재 메인과 작업을 업데이트해야 합니다:
+
+```bash
+git fetch upstream
+git merge upstream/main
+```
+
+일반적으로, 모델 또는 구현에 관한 모든 질문은 자신의 PR에서 해야 하며, PR에서 토론되고 해결되어야 합니다. 이렇게 하면 Hugging Face 팀이 새로운 코드를 커밋하거나 질문을 할 때 항상 알림을 받을 수 있습니다. Hugging Face 팀에게 문제 또는 질문을 효율적으로 이해할 수 있도록 추가한 코드를 명시하는 것이 도움이 될 때가 많습니다.
+
+이를 위해, 변경 사항을 모두 볼 수 있는 "Files changed" 탭으로 이동하여 질문하고자 하는 줄로 이동한 다음 "+" 기호를 클릭하여 코멘트를 추가할 수 있습니다. 질문이나 문제가 해결되면, 생성된 코멘트의 "Resolve" 버튼을 클릭할 수 있습니다.
+
+마찬가지로, Hugging Face 팀은 코드를 리뷰할 때 코멘트를 남길 것입니다. 우리는 PR에서 대부분의 질문을 GitHub에서 묻는 것을 권장합니다. 공개에 크게 도움이 되지 않는 매우 일반적인 질문의 경우, Slack이나 이메일을 통해 Hugging Face 팀에게 문의할 수 있습니다.
+
+**5. brand_new_bert에 대해 생성된 모델 코드를 적용하기**
+
+먼저, 우리는 모델 자체에만 초점을 맞추고 토크나이저에 대해서는 신경 쓰지 않을 것입니다. 모든 관련 코드는 다음의 생성된 파일에서 찾을 수 있습니다: `src/transformers/models/brand_new_bert/modeling_brand_new_bert.py` 및 `src/transformers/models/brand_new_bert/configuration_brand_new_bert.py`.
+
+이제 마침내 코딩을 시작할 수 있습니다 :). `src/transformers/models/brand_new_bert/modeling_brand_new_bert.py`의 생성된 코드는 인코더 전용 모델인 경우 BERT와 동일한 아키텍처를 가지거나, 인코더-디코더 모델인 경우 BART와 동일한 아키텍처를 가질 것입니다. 이 시점에서, 모델의 이론적 측면에 대해 배운 내용을 다시 상기해야 합니다: *모델이 BERT 또는 BART와 어떻게 다른가요?*. 자주 변경해야 하는 것은 *self-attention* 레이어, 정규화 레이어의 순서 등을 변경하는 것입니다. 다시 말하지만, 자신의 모델을 구현하는 데 도움이 되도록 Transformers에서 이미 존재하는 모델의 유사한 아키텍처를 살펴보는 것이 유용할 수 있습니다.
+
+**참고로** 이 시점에서, 코드가 완전히 정확하거나 깨끗하다고 확신할 필요는 없습니다. 오히려 처음에는 원본 코드의 첫 번째 *불완전하고* 복사된 버전을 `src/transformers/models/brand_new_bert/modeling_brand_new_bert.py`에 추가하는 것이 좋습니다. 필요한 모든 코드가 추가될 때까지 이러한 작업을 진행한 후, 다음 섹션에서 설명한 변환 스크립트를 사용하여 코드를 점진적으로 개선하고 수정하는 것이 훨씬 효율적입니다. 이 시점에서 작동해야 하는 유일한 것은 다음 명령이 작동하는 것입니다:
+
+```python
+from transformers import BrandNewBertModel, BrandNewBertConfig
+
+model = BrandNewBertModel(BrandNewBertConfig())
+```
+
+위의 명령은 `BrandNewBertConfig()`에 정의된 기본 매개변수에 따라 무작위 가중치로 모델을 생성하며, 이로써 모든 구성 요소의 `init()` 메서드가 작동함을 보장합니다.
+
+모든 무작위 초기화는 `BrandnewBertPreTrainedModel` 클래스의 `_init_weights` 메서드에서 수행되어야 합니다. 이 메서드는 구성 설정 변수에 따라 모든 리프 모듈을 초기화해야 합니다. BERT의 `_init_weights` 메서드 예제는 다음과 같습니다:
+
+```py
+def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+ elif isinstance(module, nn.Embedding):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.padding_idx is not None:
+ module.weight.data[module.padding_idx].zero_()
+ elif isinstance(module, nn.LayerNorm):
+ module.bias.data.zero_()
+ module.weight.data.fill_(1.0)
+```
+
+몇 가지 모듈에 대해 특별한 초기화가 필요한 경우 사용자 정의 방식을 사용할 수도 있습니다. 예를 들어, `Wav2Vec2ForPreTraining`에서 마지막 두 개의 선형 레이어는 일반적인 PyTorch `nn.Linear`의 초기화를 가져야 하지만, 다른 모든 레이어는 위와 같은 초기화를 사용해야 합니다. 이는 다음과 같이 코드화됩니다:
+
+```py
+def _init_weights(self, module):
+ """Initialize the weights"""
+ if isinstance(module, Wav2Vec2ForPreTraining):
+ module.project_hid.reset_parameters()
+ module.project_q.reset_parameters()
+ module.project_hid._is_hf_initialized = True
+ module.project_q._is_hf_initialized = True
+ elif isinstance(module, nn.Linear):
+ module.weight.data.normal_(mean=0.0, std=self.config.initializer_range)
+ if module.bias is not None:
+ module.bias.data.zero_()
+```
+
+`_is_hf_initialized` 플래그는 서브모듈을 한 번만 초기화하도록 내부적으로 사용됩니다. `module.project_q` 및 `module.project_hid`에 대해 `True`로 설정함으로써, 우리가 수행한 사용자 정의 초기화가 이후에 덮어쓰이지 않도록 합니다. 즉, `_init_weights` 함수가 이들에게 적용되지 않습니다.
+
+**6. 변환 스크립트 작성하기**
+
+다음으로, 디버그에 사용한 체크포인트를 기존 저장소에서 만든 🤗 Transformers 구현과 호환되는 체크포인트로 변환할 수 있는 변환 스크립트를 작성해야 합니다. 변환 스크립트를 처음부터 작성하는 것보다는 *brand_new_bert*와 동일한 프레임워크로 작성된 유사한 모델을 변환한 기존 변환 스크립트를 찾아보는 것이 좋습니다. 일반적으로 기존 변환 스크립트를 복사하여 사용 사례에 맞게 약간 수정하는 것으로 충분합니다. 모델에 대해 유사한 기존 변환 스크립트를 어디에서 찾을 수 있는지 Hugging Face 팀에게 문의하는 것을 망설이지 마세요.
+
+- TensorFlow에서 PyTorch로 모델을 이전하는 경우, 좋은 참고 자료로 BERT의 변환 스크립트 [여기](https://github.com/huggingface/transformers/blob/7acfa95afb8194f8f9c1f4d2c6028224dbed35a2/src/transformers/models/bert/modeling_bert.py#L91)를 참조할 수 있습니다.
+- PyTorch에서 PyTorch로 모델을 이전하는 경우, 좋은 참고 자료로 BART의 변환 스크립트 [여기](https://github.com/huggingface/transformers/blob/main/src/transformers/models/bart/convert_bart_original_pytorch_checkpoint_to_pytorch.py)를 참조할 수 있습니다.
+
+다음에서는 PyTorch 모델이 레이어 가중치를 저장하고 레이어 이름을 정의하는 방법에 대해 간단히 설명하겠습니다. PyTorch에서 레이어의 이름은 레이어에 지정한 클래스 속성의 이름으로 정의됩니다. 다음과 같이 PyTorch에서 `SimpleModel`이라는 더미 모델을 정의해 봅시다:
+
+```python
+from torch import nn
+
+
+class SimpleModel(nn.Module):
+ def __init__(self):
+ super().__init__()
+ self.dense = nn.Linear(10, 10)
+ self.intermediate = nn.Linear(10, 10)
+ self.layer_norm = nn.LayerNorm(10)
+```
+
+이제 이 모델 정의의 인스턴스를 생성할 수 있으며 `dense`, `intermediate`, `layer_norm` 등의 가중치가 랜덤하게 할당됩니다. 모델을 출력하여 아키텍처를 확인할 수 있습니다.
+
+```python
+model = SimpleModel()
+
+print(model)
+```
+
+이는 다음과 같이 출력됩니다:
+
+```
+SimpleModel(
+ (dense): Linear(in_features=10, out_features=10, bias=True)
+ (intermediate): Linear(in_features=10, out_features=10, bias=True)
+ (layer_norm): LayerNorm((10,), eps=1e-05, elementwise_affine=True)
+)
+```
+
+우리는 레이어의 이름이 PyTorch에서 클래스 속성의 이름으로 정의되어 있는 것을 볼 수 있습니다. 특정 레이어의 가중치 값을 출력하여 확인할 수 있습니다:
+
+```python
+print(model.dense.weight.data)
+```
+
+가중치가 무작위로 초기화되었음을 확인할 수 있습니다.
+
+```
+tensor([[-0.0818, 0.2207, -0.0749, -0.0030, 0.0045, -0.1569, -0.1598, 0.0212,
+ -0.2077, 0.2157],
+ [ 0.1044, 0.0201, 0.0990, 0.2482, 0.3116, 0.2509, 0.2866, -0.2190,
+ 0.2166, -0.0212],
+ [-0.2000, 0.1107, -0.1999, -0.3119, 0.1559, 0.0993, 0.1776, -0.1950,
+ -0.1023, -0.0447],
+ [-0.0888, -0.1092, 0.2281, 0.0336, 0.1817, -0.0115, 0.2096, 0.1415,
+ -0.1876, -0.2467],
+ [ 0.2208, -0.2352, -0.1426, -0.2636, -0.2889, -0.2061, -0.2849, -0.0465,
+ 0.2577, 0.0402],
+ [ 0.1502, 0.2465, 0.2566, 0.0693, 0.2352, -0.0530, 0.1859, -0.0604,
+ 0.2132, 0.1680],
+ [ 0.1733, -0.2407, -0.1721, 0.1484, 0.0358, -0.0633, -0.0721, -0.0090,
+ 0.2707, -0.2509],
+ [-0.1173, 0.1561, 0.2945, 0.0595, -0.1996, 0.2988, -0.0802, 0.0407,
+ 0.1829, -0.1568],
+ [-0.1164, -0.2228, -0.0403, 0.0428, 0.1339, 0.0047, 0.1967, 0.2923,
+ 0.0333, -0.0536],
+ [-0.1492, -0.1616, 0.1057, 0.1950, -0.2807, -0.2710, -0.1586, 0.0739,
+ 0.2220, 0.2358]]).
+```
+
+변환 스크립트에서는 이러한 무작위로 초기화된 가중치를 체크포인트의 해당 레이어의 정확한 가중치로 채워야 합니다. 예를 들면 다음과 같습니다:
+
+```python
+# retrieve matching layer weights, e.g. by
+# recursive algorithm
+layer_name = "dense"
+pretrained_weight = array_of_dense_layer
+
+model_pointer = getattr(model, "dense")
+
+model_pointer.weight.data = torch.from_numpy(pretrained_weight)
+```
+
+이렇게 하면 PyTorch 모델의 무작위로 초기화된 각 가중치와 해당 체크포인트 가중치가 **모양과 이름** 모두에서 정확히 일치하는지 확인해야 합니다. 이를 위해 모양에 대한 assert 문을 추가하고 체크포인트 가중치의 이름을 출력해야 합니다. 예를 들어 다음과 같은 문장을 추가해야 합니다:
+
+```python
+assert (
+ model_pointer.weight.shape == pretrained_weight.shape
+), f"Pointer shape of random weight {model_pointer.shape} and array shape of checkpoint weight {pretrained_weight.shape} mismatched"
+```
+
+또한 두 가중치의 이름을 출력하여 일치하는지 확인해야 합니다. *예시*:
+
+```python
+logger.info(f"Initialize PyTorch weight {layer_name} from {pretrained_weight.name}")
+```
+
+모양 또는 이름이 일치하지 않는 경우, 랜덤으로 초기화된 레이어에 잘못된 체크포인트 가중치를 할당한 것으로 추측됩니다.
+
+잘못된 모양은 `BrandNewBertConfig()`의 구성 매개변수 설정이 변환하려는 체크포인트에 사용된 설정과 정확히 일치하지 않기 때문일 가능성이 가장 큽니다. 그러나 PyTorch의 레이어 구현 자체에서 가중치를 전치해야 할 수도 있습니다.
+
+마지막으로, **모든** 필요한 가중치가 초기화되었는지 확인하고 초기화에 사용되지 않은 모든 체크포인트 가중치를 출력하여 모델이 올바르게 변환되었는지 확인해야 합니다. 잘못된 모양 문장이나 잘못된 이름 할당으로 인해 변환 시도가 실패하는 것은 완전히 정상입니다. 이는 `BrandNewBertConfig()`에서 잘못된 매개변수를 사용하거나 🤗 Transformers 구현에서 잘못된 아키텍처, 🤗 Transformers 구현의 구성 요소 중 하나의 `init()` 함수에 버그가 있는 경우이거나 체크포인트 가중치 중 하나를 전치해야 하는 경우일 가능성이 가장 높습니다.
+
+이 단계는 이전 단계와 함께 반복되어야 하며 모든 체크포인트의 가중치가 Transformers 모델에 올바르게 로드되었을 때까지 계속되어야 합니다. 🤗 Transformers 구현에 체크포인트를 올바르게 로드한 후에는 `/path/to/converted/checkpoint/folder`와 같은 원하는 폴더에 모델을 저장할 수 있어야 합니다. 해당 폴더에는 `pytorch_model.bin` 파일과 `config.json` 파일이 모두 포함되어야 합니다.
+
+```python
+model.save_pretrained("/path/to/converted/checkpoint/folder")
+```
+
+**7. 순방향 패스 구현하기**
+
+🤗 Transformers 구현에 사전 훈련된 가중치를 정확하게 로드한 후에는 순방향 패스가 올바르게 구현되었는지 확인해야 합니다. [원본 저장소에 익숙해지기](#3-4-run-a-pretrained-checkpoint-using-the-original-repository)에서 이미 원본 저장소를 사용하여 모델의 순방향 패스를 실행하는 스크립트를 만들었습니다. 이제 원본 대신 🤗 Transformers 구현을 사용하는 유사한 스크립트를 작성해야 합니다. 다음과 같이 작성되어야 합니다:
+
+```python
+model = BrandNewBertModel.from_pretrained("/path/to/converted/checkpoint/folder")
+input_ids = [0, 4, 4, 3, 2, 4, 1, 7, 19]
+output = model(input_ids).last_hidden_states
+```
+
+🤗 Transformers 구현과 원본 모델 구현이 처음부터 정확히 동일한 출력을 제공하지 않거나 순방향 패스에서 오류가 발생할 가능성이 매우 높습니다. 실망하지 마세요. 예상된 일입니다! 먼저, 순방향 패스에서 오류가 발생하지 않도록 해야 합니다. 종종 잘못된 차원이 사용되어 *차원 불일치* 오류가 발생하거나 잘못된 데이터 유형 개체가 사용되는 경우가 있습니다. 예를 들면 `torch.long` 대신에 `torch.float32`가 사용된 경우입니다. 해결할 수 없는 오류가 발생하면 Hugging Face 팀에 도움을 요청하는 것이 좋습니다.
+
+🤗 Transformers 구현이 올바르게 작동하는지 확인하는 마지막 단계는 출력이 `1e-3`의 정밀도로 동일한지 확인하는 것입니다. 먼저, 출력 모양이 동일하도록 보장해야 합니다. 즉, 🤗 Transformers 구현 스크립트와 원본 구현 사이에서 `outputs.shape`는 동일한 값을 반환해야 합니다. 그 다음으로, 출력 값이 동일하도록 해야 합니다. 이는 새로운 모델을 추가할 때 가장 어려운 부분 중 하나입니다. 출력이 동일하지 않은 일반적인 실수 사례는 다음과 같습니다:
+
+- 일부 레이어가 추가되지 않았습니다. 즉, *활성화* 레이어가 추가되지 않았거나 잔차 연결이 빠졌습니다.
+- 단어 임베딩 행렬이 연결되지 않았습니다.
+- 잘못된 위치 임베딩이 사용되었습니다. 원본 구현에서는 오프셋을 사용합니다.
+- 순방향 패스 중에 Dropout이 적용되었습니다. 이를 수정하려면 *model.training이 False*인지 확인하고 순방향 패스 중에 Dropout 레이어가 잘못 활성화되지 않도록 하세요. 즉, [PyTorch의 기능적 Dropout](https://pytorch.org/docs/stable/nn.functional.html?highlight=dropout#torch.nn.functional.dropout)에 *self.training*을 전달하세요.
+
+문제를 해결하는 가장 좋은 방법은 일반적으로 원본 구현과 🤗 Transformers 구현의 순방향 패스를 나란히 놓고 차이점이 있는지 확인하는 것입니다. 이상적으로는 순방향 패스의 중간 출력을 디버그/출력하여 원본 구현과 🤗 Transformers 구현의 정확한 위치를 찾을 수 있어야 합니다. 먼저, 두 스크립트의 하드코딩된 `input_ids`가 동일한지 확인하세요. 다음으로, `input_ids`의 첫 번째 변환의 출력(일반적으로 단어 임베딩)이 동일한지 확인하세요. 그런 다음 네트워크의 가장 마지막 레이어까지 진행해보세요. 어느 시점에서 두 구현 사이에 차이가 있는 것을 알게 되는데, 이는 🤗 Transformers 구현의 버그 위치를 가리킬 것입니다. 저희 경험상으로는 원본 구현과 🤗 Transformers 구현 모두에서 동일한 위치에 많은 출력 문을 추가하고 이들의 중간 표현에 대해 동일한 값을 보이는 출력 문을 연속적으로 제거하는 것이 간단하고 효과적인 방법입니다.
+
+`torch.allclose(original_output, output, atol=1e-3)`로 출력을 확인하여 두 구현이 동일한 출력을 하는 것을 확신한다면, 가장 어려운 부분은 끝났습니다! 축하드립니다. 남은 작업은 쉬운 일이 될 것입니다 😊.
+
+**8. 필요한 모든 모델 테스트 추가하기**
+
+이 시점에서 새로운 모델을 성공적으로 추가했습니다. 그러나 해당 모델이 요구되는 디자인에 완전히 부합하지 않을 수도 있습니다. 🤗 Transformers와 완벽하게 호환되는 구현인지 확인하기 위해 모든 일반 테스트를 통과해야 합니다. Cookiecutter는 아마도 모델을 위한 테스트 파일을 자동으로 추가했을 것입니다. 아마도 `tests/models/brand_new_bert/test_modeling_brand_new_bert.py`와 같은 경로에 위치할 것입니다. 이 테스트 파일을 실행하여 일반 테스트가 모두 통과하는지 확인하세요.
+
+```bash
+pytest tests/models/brand_new_bert/test_modeling_brand_new_bert.py
+```
+
+모든 일반 테스트를 수정한 후, 이제 수행한 작업을 충분히 테스트하여 다음 사항을 보장해야 합니다.
+
+- a) 커뮤니티가 *brand_new_bert*의 특정 테스트를 살펴봄으로써 작업을 쉽게 이해할 수 있도록 함
+- b) 모델에 대한 향후 변경 사항이 모델의 중요한 기능을 손상시키지 않도록 함
+
+먼저 통합 테스트를 추가해야 합니다. 이러한 통합 테스트는 이전에 모델을 🤗 Transformers로 구현하기 위해 사용한 디버깅 스크립트와 동일한 작업을 수행합니다. Cookiecutter에 이미 이러한 모델 테스트의 템플릿인 `BrandNewBertModelIntegrationTests`가 추가되어 있으며, 여러분이 작성해야 할 내용으로만 채워 넣으면 됩니다. 이러한 테스트가 통과하는지 확인하려면 다음을 실행하세요.
+
+```bash
+RUN_SLOW=1 pytest -sv tests/models/brand_new_bert/test_modeling_brand_new_bert.py::BrandNewBertModelIntegrationTests
+```
+
+
+
+Windows를 사용하는 경우 `RUN_SLOW=1`을 `SET RUN_SLOW=1`로 바꿔야 합니다.
+
+
+
+둘째로, *brand_new_bert*에 특화된 모든 기능도 별도의 테스트에서 추가로 테스트해야 합니다. 이 부분은 종종 잊히는데, 두 가지 측면에서 굉장히 유용합니다.
+
+- *brand_new_bert*의 특수 기능이 어떻게 작동해야 하는지 보여줌으로써 커뮤니티에게 모델 추가 과정에서 습득한 지식을 전달하는 데 도움이 됩니다.
+- 향후 기여자는 이러한 특수 테스트를 실행하여 모델에 대한 변경 사항을 빠르게 테스트할 수 있습니다.
+
+
+**9. 토크나이저 구현하기**
+
+다음으로, *brand_new_bert*의 토크나이저를 추가해야 합니다. 보통 토크나이저는 🤗 Transformers의 기존 토크나이저와 동일하거나 매우 유사합니다.
+
+토크나이저가 올바르게 작동하는지 확인하기 위해 먼저 원본 리포지토리에서 문자열을 입력하고 `input_ids`를 반환하는 스크립트를 생성하는 것이 좋습니다. 다음과 같은 유사한 스크립트일 수 있습니다 (의사 코드로 작성):
+
+```python
+input_str = "This is a long example input string containing special characters .$?-, numbers 2872 234 12 and words."
+model = BrandNewBertModel.load_pretrained_checkpoint("/path/to/checkpoint/")
+input_ids = model.tokenize(input_str)
+```
+
+원본 리포지토리를 자세히 살펴보고 올바른 토크나이저 함수를 찾거나, 복제본에서 변경 사항을 적용하여 `input_ids`만 출력하도록 해야 합니다. 원본 리포지토리를 사용하는 기능적인 토큰화 스크립트를 작성한 후, 🤗 Transformers의 유사한 스크립트를 생성해야 합니다. 다음과 같이 작성되어야 합니다:
+
+```python
+from transformers import BrandNewBertTokenizer
+
+input_str = "This is a long example input string containing special characters .$?-, numbers 2872 234 12 and words."
+
+tokenizer = BrandNewBertTokenizer.from_pretrained("/path/to/tokenizer/folder/")
+
+input_ids = tokenizer(input_str).input_ids
+```
+
+두 개의 `input_ids`가 동일한 값을 반환할 때, 마지막 단계로 토크나이저 테스트 파일도 추가해야 합니다.
+
+*brand_new_bert*의 모델링 테스트 파일과 유사하게, *brand_new_bert*의 토크나이제이션 테스트 파일에는 몇 가지 하드코딩된 통합 테스트가 포함되어야 합니다.
+
+**10. 종단 간 통합 테스트 실행**
+
+토크나이저를 추가한 후에는 모델과 토크나이저를 사용하여 몇 가지 종단 간 통합 테스트를 추가해야 합니다. `tests/models/brand_new_bert/test_modeling_brand_new_bert.py`에 추가해주세요. 이러한 테스트는 🤗 Transformers 구현이 예상대로 작동하는지를 의미 있는 text-to-text 예시로 보여줘야 합니다. 그 예시로는 *예를 들어* source-to-target 번역 쌍, article-to-summary 쌍, question-to-answer 쌍 등이 포함될 수 있습니다. 불러온 체크포인트 중 어느 것도 다운스트림 작업에서 미세 조정되지 않았다면, 모델 테스트만으로 충분합니다. 모델이 완전히 기능을 갖추었는지 확인하기 위해 마지막 단계로 GPU에서 모든 테스트를 실행하는 것이 좋습니다. 모델의 내부 텐서의 일부에 `.to(self.device)` 문을 추가하는 것을 잊었을 수 있으며, 이 경우 테스트에서 오류로 표시됩니다. GPU에 액세스할 수 없는 경우, Hugging Face 팀이 테스트를 대신 실행할 수 있습니다.
+
+**11. 기술문서 추가**
+
+이제 *brand_new_bert*에 필요한 모든 기능이 추가되었습니다. 거의 끝났습니다! 추가해야 할 것은 멋진 기술문서과 기술문서 페이지입니다. Cookiecutter가 `docs/source/model_doc/brand_new_bert.md`라는 템플릿 파일을 추가해줬을 것입니다. 이 페이지를 사용하기 전에 모델을 사용하는 사용자들은 일반적으로 이 페이지를 먼저 확인합니다. 따라서 문서는 이해하기 쉽고 간결해야 합니다. 모델을 사용하는 방법을 보여주기 위해 *팁*을 추가하는 것이 커뮤니티에 매우 유용합니다. 독스트링에 관련하여 Hugging Face 팀에 문의하는 것을 주저하지 마세요.
+
+다음으로, `src/transformers/models/brand_new_bert/modeling_brand_new_bert.py`에 추가된 독스트링이 올바르며 필요한 모든 입력 및 출력을 포함하도록 확인하세요. [여기](writing-documentation)에서 우리의 문서 작성 가이드와 독스트링 형식에 대한 상세 가이드가 있습니다. 문서는 일반적으로 커뮤니티와 모델의 첫 번째 접점이기 때문에, 문서는 적어도 코드만큼의 주의를 기울여야 합니다.
+
+**코드 리팩토링**
+
+좋아요, 이제 *brand_new_bert*를 위한 모든 필요한 코드를 추가했습니다. 이 시점에서 다음을 실행하여 잠재적으로 잘못된 코드 스타일을 수정해야 합니다:
+
+그리고 코딩 스타일이 품질 점검을 통과하는지 확인하기 위해 다음을 실행하고 확인해야 합니다:
+
+```bash
+make style
+```
+
+🤗 Transformers에는 여전히 실패할 수 있는 몇 가지 매우 엄격한 디자인 테스트가 있습니다. 이는 독스트링에 누락된 정보나 잘못된 명명 때문에 종종 발생합니다. 여기서 막히면 Hugging Face 팀이 도움을 줄 것입니다.
+
+```bash
+make quality
+```
+
+마지막으로, 코드가 정확히 작동하는 것을 확인한 후에는 항상 코드를 리팩토링하는 것이 좋은 생각입니다. 모든 테스트가 통과된 지금은 추가한 코드를 다시 검토하고 리팩토링하는 좋은 시기입니다.
+
+이제 코딩 부분을 완료했습니다. 축하합니다! 🎉 멋져요! 😎
+
+**12. 모델을 모델 허브에 업로드하세요**
+
+이 마지막 파트에서는 모든 체크포인트를 변환하여 모델 허브에 업로드하고 각 업로드된 모델 체크포인트에 대한 모델 카드를 추가해야 합니다. [Model sharing and uploading Page](model_sharing)를 읽고 허브 기능에 익숙해지세요. *brand_new_bert*의 저자 조직 아래에 모델을 업로드할 수 있는 필요한 액세스 권한을 얻기 위해 Hugging Face 팀과 협업해야 합니다. `transformers`의 모든 모델에 있는 `push_to_hub` 메서드는 체크포인트를 허브에 빠르고 효율적으로 업로드하는 방법입니다. 아래에 작은 코드 조각이 붙여져 있습니다:
+
+각 체크포인트에 적합한 모델 카드를 만드는 데 시간을 할애하는 것은 가치가 있습니다. 모델 카드는 체크포인트의 특성을 강조해야 합니다. *예를 들어* 이 체크포인트는 어떤 데이터셋에서 사전 훈련/세부 훈련되었는지? 이 모델은 어떤 하위 작업에서 사용해야 하는지? 그리고 모델을 올바르게 사용하는 방법에 대한 몇 가지 코드도 포함해야 합니다.
+
+```python
+brand_new_bert.push_to_hub("brand_new_bert")
+# Uncomment the following line to push to an organization.
+# brand_new_bert.push_to_hub("/brand_new_bert")
+```
+
+**13. (선택 사항) 노트북 추가**
+
+*brand_new_bert*를 다운스트림 작업에서 추론 또는 미세 조정에 사용하는 방법을 자세히 보여주는 노트북을 추가하는 것이 매우 유용합니다. 이것은 PR을 병합하는 데 필수적이지는 않지만 커뮤니티에 매우 유용합니다.
+
+**14. 완료된 PR 제출**
+
+이제 프로그래밍을 마쳤으며, 마지막 단계로 PR을 메인 브랜치에 병합해야 합니다. 보통 Hugging Face 팀은 이미 여기까지 도움을 주었을 것입니다. 그러나 PR에 멋진 설명을 추가하고 리뷰어에게 특정 디자인 선택 사항을 강조하려면 완료된 PR에 약간의 설명을 추가하는 시간을 할애하는 것이 가치가 있습니다.
+
+### 작업물을 공유하세요!! [[share-your-work]]
+
+이제 커뮤니티에서 작업물을 인정받을 시간입니다! 모델 추가 작업을 완료하는 것은 Transformers와 전체 NLP 커뮤니티에 큰 기여입니다. 당신의 코드와 이식된 사전 훈련된 모델은 수백, 심지어 수천 명의 개발자와 연구원에 의해 확실히 사용될 것입니다. 당신의 작업에 자랑스러워해야 하며 이를 커뮤니티와 공유해야 합니다.
+
+**당신은 커뮤니티 내 모든 사람들에게 매우 쉽게 접근 가능한 또 다른 모델을 만들었습니다! 🤯**
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/add_new_pipeline.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/add_new_pipeline.md
new file mode 100644
index 0000000000000000000000000000000000000000..42c9b57c9d7be675010069bc1803233befba410a
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/add_new_pipeline.md
@@ -0,0 +1,244 @@
+
+
+# 어떻게 사용자 정의 파이프라인을 생성하나요? [[how-to-create-a-custom-pipeline]]
+
+이 가이드에서는 사용자 정의 파이프라인을 어떻게 생성하고 [허브](https://hf.co/models)에 공유하거나 🤗 Transformers 라이브러리에 추가하는 방법을 살펴보겠습니다.
+
+먼저 파이프라인이 수용할 수 있는 원시 입력을 결정해야 합니다.
+문자열, 원시 바이트, 딕셔너리 또는 가장 원하는 입력일 가능성이 높은 것이면 무엇이든 가능합니다.
+이 입력을 가능한 한 순수한 Python 형식으로 유지해야 (JSON을 통해 다른 언어와도) 호환성이 좋아집니다.
+이것이 전처리(`preprocess`) 파이프라인의 입력(`inputs`)이 될 것입니다.
+
+그런 다음 `outputs`를 정의하세요.
+`inputs`와 같은 정책을 따르고, 간단할수록 좋습니다.
+이것이 후처리(`postprocess`) 메소드의 출력이 될 것입니다.
+
+먼저 4개의 메소드(`preprocess`, `_forward`, `postprocess` 및 `_sanitize_parameters`)를 구현하기 위해 기본 클래스 `Pipeline`을 상속하여 시작합니다.
+
+
+```python
+from transformers import Pipeline
+
+
+class MyPipeline(Pipeline):
+ def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "maybe_arg" in kwargs:
+ preprocess_kwargs["maybe_arg"] = kwargs["maybe_arg"]
+ return preprocess_kwargs, {}, {}
+
+ def preprocess(self, inputs, maybe_arg=2):
+ model_input = Tensor(inputs["input_ids"])
+ return {"model_input": model_input}
+
+ def _forward(self, model_inputs):
+ # model_inputs == {"model_input": model_input}
+ outputs = self.model(**model_inputs)
+ # Maybe {"logits": Tensor(...)}
+ return outputs
+
+ def postprocess(self, model_outputs):
+ best_class = model_outputs["logits"].softmax(-1)
+ return best_class
+```
+
+이 분할 구조는 CPU/GPU에 대한 비교적 원활한 지원을 제공하는 동시에, 다른 스레드에서 CPU에 대한 사전/사후 처리를 수행할 수 있게 지원하는 것입니다.
+
+`preprocess`는 원래 정의된 입력을 가져와 모델에 공급할 수 있는 형식으로 변환합니다.
+더 많은 정보를 포함할 수 있으며 일반적으로 `Dict` 형태입니다.
+
+`_forward`는 구현 세부 사항이며 직접 호출할 수 없습니다.
+`forward`는 예상 장치에서 모든 것이 작동하는지 확인하기 위한 안전장치가 포함되어 있어 선호되는 호출 메소드입니다.
+실제 모델과 관련된 것은 `_forward` 메소드에 속하며, 나머지는 전처리/후처리 과정에 있습니다.
+
+`postprocess` 메소드는 `_forward`의 출력을 가져와 이전에 결정한 최종 출력 형식으로 변환합니다.
+
+`_sanitize_parameters`는 초기화 시간에 `pipeline(...., maybe_arg=4)`이나 호출 시간에 `pipe = pipeline(...); output = pipe(...., maybe_arg=4)`과 같이, 사용자가 원하는 경우 언제든지 매개변수를 전달할 수 있도록 허용합니다.
+
+`_sanitize_parameters`의 반환 값은 `preprocess`, `_forward`, `postprocess`에 직접 전달되는 3개의 kwargs 딕셔너리입니다.
+호출자가 추가 매개변수로 호출하지 않았다면 아무것도 채우지 마십시오.
+이렇게 하면 항상 더 "자연스러운" 함수 정의의 기본 인수를 유지할 수 있습니다.
+
+분류 작업에서 `top_k` 매개변수가 대표적인 예입니다.
+
+```python
+>>> pipe = pipeline("my-new-task")
+>>> pipe("This is a test")
+[{"label": "1-star", "score": 0.8}, {"label": "2-star", "score": 0.1}, {"label": "3-star", "score": 0.05}
+{"label": "4-star", "score": 0.025}, {"label": "5-star", "score": 0.025}]
+
+>>> pipe("This is a test", top_k=2)
+[{"label": "1-star", "score": 0.8}, {"label": "2-star", "score": 0.1}]
+```
+
+이를 달성하기 위해 우리는 `postprocess` 메소드를 기본 매개변수인 `5`로 업데이트하고 `_sanitize_parameters`를 수정하여 이 새 매개변수를 허용합니다.
+
+
+```python
+def postprocess(self, model_outputs, top_k=5):
+ best_class = model_outputs["logits"].softmax(-1)
+ # top_k를 처리하는 로직 추가
+ return best_class
+
+
+def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "maybe_arg" in kwargs:
+ preprocess_kwargs["maybe_arg"] = kwargs["maybe_arg"]
+
+ postprocess_kwargs = {}
+ if "top_k" in kwargs:
+ postprocess_kwargs["top_k"] = kwargs["top_k"]
+ return preprocess_kwargs, {}, postprocess_kwargs
+```
+
+입/출력을 가능한 한 간단하고 완전히 JSON 직렬화 가능한 형식으로 유지하려고 노력하십시오.
+이렇게 하면 사용자가 새로운 종류의 개체를 이해하지 않고도 파이프라인을 쉽게 사용할 수 있습니다.
+또한 사용 용이성을 위해 여러 가지 유형의 인수(오디오 파일은 파일 이름, URL 또는 순수한 바이트일 수 있음)를 지원하는 것이 비교적 일반적입니다.
+
+
+
+## 지원되는 작업 목록에 추가하기 [[adding-it-to-the-list-of-supported-tasks]]
+
+`new-task`를 지원되는 작업 목록에 등록하려면 `PIPELINE_REGISTRY`에 추가해야 합니다:
+
+```python
+from transformers.pipelines import PIPELINE_REGISTRY
+
+PIPELINE_REGISTRY.register_pipeline(
+ "new-task",
+ pipeline_class=MyPipeline,
+ pt_model=AutoModelForSequenceClassification,
+)
+```
+
+원하는 경우 기본 모델을 지정할 수 있으며, 이 경우 특정 개정(분기 이름 또는 커밋 해시일 수 있음, 여기서는 "abcdef")과 타입을 함께 가져와야 합니다:
+
+```python
+PIPELINE_REGISTRY.register_pipeline(
+ "new-task",
+ pipeline_class=MyPipeline,
+ pt_model=AutoModelForSequenceClassification,
+ default={"pt": ("user/awesome_model", "abcdef")},
+ type="text", # 현재 지원 유형: text, audio, image, multimodal
+)
+```
+
+## Hub에 파이프라인 공유하기 [[share-your-pipeline-on-the-hub]]
+
+Hub에 사용자 정의 파이프라인을 공유하려면 `Pipeline` 하위 클래스의 사용자 정의 코드를 Python 파일에 저장하기만 하면 됩니다.
+예를 들어, 다음과 같이 문장 쌍 분류를 위한 사용자 정의 파이프라인을 사용한다고 가정해 보겠습니다:
+
+```py
+import numpy as np
+
+from transformers import Pipeline
+
+
+def softmax(outputs):
+ maxes = np.max(outputs, axis=-1, keepdims=True)
+ shifted_exp = np.exp(outputs - maxes)
+ return shifted_exp / shifted_exp.sum(axis=-1, keepdims=True)
+
+
+class PairClassificationPipeline(Pipeline):
+ def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "second_text" in kwargs:
+ preprocess_kwargs["second_text"] = kwargs["second_text"]
+ return preprocess_kwargs, {}, {}
+
+ def preprocess(self, text, second_text=None):
+ return self.tokenizer(text, text_pair=second_text, return_tensors=self.framework)
+
+ def _forward(self, model_inputs):
+ return self.model(**model_inputs)
+
+ def postprocess(self, model_outputs):
+ logits = model_outputs.logits[0].numpy()
+ probabilities = softmax(logits)
+
+ best_class = np.argmax(probabilities)
+ label = self.model.config.id2label[best_class]
+ score = probabilities[best_class].item()
+ logits = logits.tolist()
+ return {"label": label, "score": score, "logits": logits}
+```
+
+구현은 프레임워크에 구애받지 않으며, PyTorch와 TensorFlow 모델에 대해 작동합니다.
+이를 `pair_classification.py`라는 파일에 저장한 경우, 다음과 같이 가져오고 등록할 수 있습니다:
+
+```py
+from pair_classification import PairClassificationPipeline
+from transformers.pipelines import PIPELINE_REGISTRY
+from transformers import AutoModelForSequenceClassification, TFAutoModelForSequenceClassification
+
+PIPELINE_REGISTRY.register_pipeline(
+ "pair-classification",
+ pipeline_class=PairClassificationPipeline,
+ pt_model=AutoModelForSequenceClassification,
+ tf_model=TFAutoModelForSequenceClassification,
+)
+```
+
+이 작업이 완료되면 사전훈련된 모델과 함께 사용할 수 있습니다.
+예를 들어, `sgugger/finetuned-bert-mrpc`은 MRPC 데이터 세트에서 미세 조정되어 문장 쌍을 패러프레이즈인지 아닌지를 분류합니다.
+
+```py
+from transformers import pipeline
+
+classifier = pipeline("pair-classification", model="sgugger/finetuned-bert-mrpc")
+```
+
+그런 다음 `push_to_hub` 메소드를 사용하여 허브에 공유할 수 있습니다:
+
+```py
+classifier.push_to_hub("test-dynamic-pipeline")
+```
+
+이렇게 하면 "test-dynamic-pipeline" 폴더 내에 `PairClassificationPipeline`을 정의한 파일이 복사되며, 파이프라인의 모델과 토크나이저도 저장한 후, `{your_username}/test-dynamic-pipeline` 저장소에 있는 모든 것을 푸시합니다.
+이후에는 `trust_remote_code=True` 옵션만 제공하면 누구나 사용할 수 있습니다.
+
+```py
+from transformers import pipeline
+
+classifier = pipeline(model="{your_username}/test-dynamic-pipeline", trust_remote_code=True)
+```
+
+## 🤗 Transformers에 파이프라인 추가하기 [[add-the-pipeline-to-transformers]]
+
+🤗 Transformers에 사용자 정의 파이프라인을 기여하려면, `pipelines` 하위 모듈에 사용자 정의 파이프라인 코드와 함께 새 모듈을 추가한 다음, `pipelines/__init__.py`에서 정의된 작업 목록에 추가해야 합니다.
+
+그런 다음 테스트를 추가해야 합니다.
+`tests/test_pipelines_MY_PIPELINE.py`라는 새 파일을 만들고 다른 테스트와 예제를 함께 작성합니다.
+
+`run_pipeline_test` 함수는 매우 일반적이며, `model_mapping` 및 `tf_model_mapping`에서 정의된 가능한 모든 아키텍처의 작은 무작위 모델에서 실행됩니다.
+
+이는 향후 호환성을 테스트하는 데 매우 중요하며, 누군가 `XXXForQuestionAnswering`을 위한 새 모델을 추가하면 파이프라인 테스트가 해당 모델에서 실행을 시도한다는 의미입니다.
+모델이 무작위이기 때문에 실제 값을 확인하는 것은 불가능하므로, 단순히 파이프라인 출력 `TYPE`과 일치시키기 위한 도우미 `ANY`가 있습니다.
+
+또한 2개(이상적으로는 4개)의 테스트를 구현해야 합니다.
+
+- `test_small_model_pt`: 이 파이프라인에 대한 작은 모델 1개를 정의(결과가 의미 없어도 상관없음)하고 파이프라인 출력을 테스트합니다.
+결과는 `test_small_model_tf`와 동일해야 합니다.
+- `test_small_model_tf`: 이 파이프라인에 대한 작은 모델 1개를 정의(결과가 의미 없어도 상관없음)하고 파이프라인 출력을 테스트합니다.
+결과는 `test_small_model_pt`와 동일해야 합니다.
+- `test_large_model_pt`(`선택사항`): 결과가 의미 있을 것으로 예상되는 실제 파이프라인에서 파이프라인을 테스트합니다.
+이러한 테스트는 속도가 느리므로 이를 표시해야 합니다.
+여기서의 목표는 파이프라인을 보여주고 향후 릴리즈에서의 변화가 없는지 확인하는 것입니다.
+- `test_large_model_tf`(`선택사항`): 결과가 의미 있을 것으로 예상되는 실제 파이프라인에서 파이프라인을 테스트합니다.
+이러한 테스트는 속도가 느리므로 이를 표시해야 합니다.
+여기서의 목표는 파이프라인을 보여주고 향후 릴리즈에서의 변화가 없는지 확인하는 것입니다.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/attention.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/attention.md
new file mode 100644
index 0000000000000000000000000000000000000000..d9a5eeee1b73eada3d0d704b2ff6744f545c6d2b
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/attention.md
@@ -0,0 +1,54 @@
+
+
+# 어텐션 메커니즘[[attention_mechanisms]]
+
+대부분의 트랜스포머 모델은 정방행렬인 전체 어텐션을 사용합니다.
+하지만 이는 긴 텍스트를 다룰 때는 큰 계산 병목 현상을 유발할 수 있습니다.
+`Longformer`와 `Reformer`는 훈련 속도를 높이기 위해 어텐션 행렬의 희소 버전을 사용하여 효율을 높이려는 모델입니다.
+
+## LSH 어텐션[[lsh_attention]]
+
+
+[Reformer](model_doc/reformer)는 LSH(Locality Sensitive Hashing) 어텐션을 사용합니다. softmax(QK^t)에서는 행렬 QK^t의 (softmax 차원에서) 가장 큰 요소들만 유용한 기여를 할 것입니다.
+따라서 각각의 쿼리 q에 대해, q와 가까운 키 k만 고려할 수 있습니다. 해시 함수는 q와 k가 가까운지 여부를 결정하는 데 사용됩니다.
+어텐션 마스크는 현재 토큰을 마스킹하여 변경됩니다. 이 때 첫 번째 위치의 토큰은 제외합니다. 왜냐하면 쿼리와 키가 동일한 값을 갖게 되기 때문입니다(서로 매우 유사함).
+해시는 약간의 무작위성을 가질 수 있으므로, 실제로는 여러 개의 해시 함수가 사용되고 (`n_rounds` 매개변수에 의해 결정됨) 그 후에 평균값을 취하게 됩니다.
+
+## 지역 어텐션[[local_attention]]
+
+[Longformer](model_doc/longformer)는 지역 어텐션을 사용합니다. 종종 특정 토큰에 대해 지역 컨텍스트(예: 왼쪽과 오른쪽에 있는 두 개의 토큰은 무엇인가요?)만으로도 작업을 수행하는데 충분합니다.
+또한 작은 창(window)을 가진 어텐션 레이어를 쌓음으로써 마지막 레이어는 창 내의 토큰뿐만 아니라 더 많은 수의 토큰에 대한 수용 영역(receptive field)을 갖게 되어 전체 문장의 표현을 구축할 수 있습니다.
+
+사전에 선택된 일부 입력 토큰들은 전역 어텐션을 받습니다. 이 몇 개의 토큰에 대해서는 어텐션 행렬이 모든 토큰에 접근할 수 있으며, 이 과정은 대칭적으로 이루어집니다.
+다른 모든 토큰들은 로컬 창 내의 토큰들에 더해 해당 특정 토큰들에도 접근할 수 있습니다. 이는 논문의 Figure 2d에서 나타나며, 아래에 샘플 어텐션 마스크가 제시되어 있습니다:
+
+
+
+
+
+
+
+적은 파라미터의 어텐션 행렬을 사용하면 모델이 더 큰 시퀀스 입력 길이를 가질 수 있습니다.
+
+## 다른 방법들[[other_tricks]]
+
+### 축별 위치 인코딩[[axial_positional_encodings]]
+
+[Reformer](model_doc/reformer)는 축별 위치 인코딩(axial positional encodings)을 사용합니다. 기존의 트랜스포머 모델에서는 위치 인코딩 행렬 E는 크기가 \\(l \times d\\)인 행렬이며,
+여기서 \\(l\\)은 시퀀스 길이(sequence length)이고 \\(d\\)는 숨겨진 상태(hidden state)의 차원입니다. 매우 긴 텍스트의 경우, 이 행렬은 매우 크며 GPU 상에서 공간을 많이 차지할 수 있습니다.
+이를 완화하기 위해, 축별 위치 인코딩은 큰 행렬 E를 두 개의 작은 행렬 E1과 E2로 분해합니다. 이때 E1의 크기는 \\(l_{1} \times d_{1}\\)이고, E2의 크기는 \\(l_{2} \times d_{2}\\)입니다.
+이때 \\(l_{1} \times l_{2} = l\\)이고 \\(d_{1} + d_{2} = d\\)(길이에 대한 곱셈 연산을 사용하면 훨씬 작아집니다). E의 시간 단계 j에 대한 임베딩은 E1에서 시간 단계 \\(j \% l1\\)의 임베딩과 E2에서 시간 단계 \\(j // l1\\)의 임베딩을 연결하여 얻습니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/autoclass_tutorial.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/autoclass_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..e41a2acc7b486b44590387fd2aa495b78b530f75
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/autoclass_tutorial.md
@@ -0,0 +1,144 @@
+
+
+# AutoClass로 사전 학습된 인스턴스 로드[[load-pretrained-instances-with-an-autoclass]]
+
+트랜스포머 아키텍처가 매우 다양하기 때문에 체크포인트에 맞는 아키텍처를 생성하는 것이 어려울 수 있습니다. 라이브러리를 쉽고 간단하며 유연하게 사용하기 위한 Transformer 핵심 철학의 일환으로, `AutoClass`는 주어진 체크포인트에서 올바른 아키텍처를 자동으로 추론하여 로드합니다. `from_pretrained()` 메서드를 사용하면 모든 아키텍처에 대해 사전 학습된 모델을 빠르게 로드할 수 있으므로 모델을 처음부터 학습하는 데 시간과 리소스를 투입할 필요가 없습니다.
+체크포인트에 구애받지 않는 코드를 생성한다는 것은 코드가 한 체크포인트에서 작동하면 아키텍처가 다르더라도 다른 체크포인트(유사한 작업에 대해 학습된 경우)에서도 작동한다는 것을 의미합니다.
+
+
+
+아키텍처는 모델의 골격을 의미하며 체크포인트는 주어진 아키텍처에 대한 가중치입니다. 예를 들어, [BERT](https://huggingface.co/google-bert/bert-base-uncased)는 아키텍처이고, `google-bert/bert-base-uncased`는 체크포인트입니다. 모델은 아키텍처 또는 체크포인트를 의미할 수 있는 일반적인 용어입니다.
+
+
+
+이 튜토리얼에서는 다음을 학습합니다:
+
+* 사전 학습된 토크나이저 로드하기.
+* 사전 학습된 이미지 프로세서 로드하기.
+* 사전 학습된 특징 추출기 로드하기.
+* 사전 훈련된 프로세서 로드하기.
+* 사전 학습된 모델 로드하기.
+
+## AutoTokenizer[[autotokenizer]]
+
+거의 모든 NLP 작업은 토크나이저로 시작됩니다. 토크나이저는 사용자의 입력을 모델에서 처리할 수 있는 형식으로 변환합니다.
+[`AutoTokenizer.from_pretrained`]로 토크나이저를 로드합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+```
+
+그리고 아래와 같이 입력을 토큰화합니다:
+
+```py
+>>> sequence = "In a hole in the ground there lived a hobbit."
+>>> print(tokenizer(sequence))
+{'input_ids': [101, 1999, 1037, 4920, 1999, 1996, 2598, 2045, 2973, 1037, 7570, 10322, 4183, 1012, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+## AutoImageProcessor[[autoimageprocessor]]
+
+비전 작업의 경우 이미지 프로세서가 이미지를 올바른 입력 형식으로 처리합니다.
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+```
+
+
+## AutoFeatureExtractor[[autofeatureextractor]]
+
+오디오 작업의 경우 특징 추출기가 오디오 신호를 올바른 입력 형식으로 처리합니다.
+
+[`AutoFeatureExtractor.from_pretrained`]로 특징 추출기를 로드합니다:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained(
+... "ehcalabres/wav2vec2-lg-xlsr-en-speech-emotion-recognition"
+... )
+```
+
+## AutoProcessor[[autoprocessor]]
+
+멀티모달 작업에는 두 가지 유형의 전처리 도구를 결합한 프로세서가 필요합니다. 예를 들어 LayoutLMV2 모델에는 이미지를 처리하는 이미지 프로세서와 텍스트를 처리하는 토크나이저가 필요하며, 프로세서는 이 두 가지를 결합합니다.
+
+[`AutoProcessor.from_pretrained()`]로 프로세서를 로드합니다:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("microsoft/layoutlmv2-base-uncased")
+```
+
+## AutoModel[[automodel]]
+
+
+
+마지막으로 AutoModelFor클래스를 사용하면 주어진 작업에 대해 미리 학습된 모델을 로드할 수 있습니다 (사용 가능한 작업의 전체 목록은 [여기](model_doc/auto)를 참조하세요). 예를 들어, [`AutoModelForSequenceClassification.from_pretrained`]를 사용하여 시퀀스 분류용 모델을 로드할 수 있습니다:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+동일한 체크포인트를 쉽게 재사용하여 다른 작업에 아키텍처를 로드할 수 있습니다:
+
+```py
+>>> from transformers import AutoModelForTokenClassification
+
+>>> model = AutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+PyTorch모델의 경우 `from_pretrained()` 메서드는 내부적으로 피클을 사용하여 안전하지 않은 것으로 알려진 `torch.load()`를 사용합니다.
+일반적으로 신뢰할 수 없는 소스에서 가져왔거나 변조되었을 수 있는 모델은 로드하지 마세요. 허깅 페이스 허브에서 호스팅되는 공개 모델의 경우 이러한 보안 위험이 부분적으로 완화되며, 각 커밋 시 멀웨어를 [검사합니다](https://huggingface.co/docs/hub/security-malware). GPG를 사용해 서명된 [커밋 검증](https://huggingface.co/docs/hub/security-gpg#signing-commits-with-gpg)과 같은 모범사례는 [문서](https://huggingface.co/docs/hub/security)를 참조하세요.
+
+텐서플로우와 Flax 체크포인트는 영향을 받지 않으며, `from_pretrained`메서드에 `from_tf` 와 `from_flax` 키워드 가변 인자를 사용하여 이 문제를 우회할 수 있습니다.
+
+
+
+일반적으로 AutoTokenizer 클래스와 AutoModelFor 클래스를 사용하여 미리 학습된 모델 인스턴스를 로드하는 것이 좋습니다. 이렇게 하면 매번 올바른 아키텍처를 로드할 수 있습니다. 다음 [튜토리얼](preprocessing)에서는 새롭게 로드한 토크나이저, 이미지 프로세서, 특징 추출기를 사용하여 미세 튜닝용 데이터 세트를 전처리하는 방법에 대해 알아봅니다.
+
+
+마지막으로 `TFAutoModelFor` 클래스를 사용하면 주어진 작업에 대해 사전 훈련된 모델을 로드할 수 있습니다. (사용 가능한 작업의 전체 목록은 [여기](model_doc/auto)를 참조하세요. 예를 들어, [`TFAutoModelForSequenceClassification.from_pretrained`]로 시퀀스 분류를 위한 모델을 로드합니다:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+쉽게 동일한 체크포인트를 재사용하여 다른 작업에 아키텍처를 로드할 수 있습니다:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+일반적으로, `AutoTokenizer`클래스와 `TFAutoModelFor` 클래스를 사용하여 미리 학습된 모델 인스턴스를 로드하는 것이 좋습니다. 이렇게 하면 매번 올바른 아키텍처를 로드할 수 있습니다. 다음 [튜토리얼](preprocessing)에서는 새롭게 로드한 토크나이저, 이미지 프로세서, 특징 추출기를 사용하여 미세 튜닝용 데이터 세트를 전처리하는 방법에 대해 알아봅니다.
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/bertology.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/bertology.md
new file mode 100644
index 0000000000000000000000000000000000000000..7b4f3dc4c4939bb44c401f96bf69f53cd179e5bd
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/bertology.md
@@ -0,0 +1,41 @@
+
+
+# BERTology
+
+BERT와 같은 대규모 트랜스포머의 내부 동작을 조사하는 연구 분야가 점점 더 중요해지고 있습니다.
+혹자는 "BERTology"라 칭하기도 합니다. 이 분야의 좋은 예시는 다음과 같습니다:
+
+
+- BERT는 고전적인 NLP 파이프라인의 재발견 - Ian Tenney, Dipanjan Das, Ellie Pavlick:
+ https://arxiv.org/abs/1905.05950
+- 16개의 헤드가 정말로 1개보다 나은가? - Paul Michel, Omer Levy, Graham Neubig:
+ https://arxiv.org/abs/1905.10650
+- BERT는 무엇을 보는가? BERT의 어텐션 분석 - Kevin Clark, Urvashi Khandelwal, Omer Levy, Christopher D. Manning:
+ https://arxiv.org/abs/1906.04341
+- CAT-probing: 프로그래밍 언어에 대해 사전훈련된 모델이 어떻게 코드 구조를 보는지 알아보기 위한 메트릭 기반 접근 방법:
+ https://arxiv.org/abs/2210.04633
+
+우리는 이 새로운 연구 분야의 발전을 돕기 위해, BERT/GPT/GPT-2 모델에 내부 표현을 살펴볼 수 있는 몇 가지 기능을 추가했습니다.
+이 기능들은 주로 Paul Michel의 훌륭한 작업을 참고하여 개발되었습니다
+(https://arxiv.org/abs/1905.10650):
+
+
+- BERT/GPT/GPT-2의 모든 은닉 상태에 접근하기,
+- BERT/GPT/GPT-2의 각 헤드의 모든 어텐션 가중치에 접근하기,
+- 헤드의 출력 값과 그래디언트를 검색하여 헤드 중요도 점수를 계산하고 https://arxiv.org/abs/1905.10650에서 설명된 대로 헤드를 제거하는 기능을 제공합니다.
+
+이러한 기능들을 이해하고 직접 사용해볼 수 있도록 [bertology.py](https://github.com/huggingface/transformers/tree/main/examples/research_projects/bertology/run_bertology.py) 예제 스크립트를 추가했습니다. 이 예제 스크립트에서는 GLUE에 대해 사전훈련된 모델에서 정보를 추출하고 모델을 가지치기(prune)해봅니다.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/big_models.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/big_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..3180b51117a97b93566775485455e157ee7bd6ff
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/big_models.md
@@ -0,0 +1,122 @@
+
+
+# 큰 모델 인스턴스화 [[instantiating-a-big-model]]
+
+매우 큰 사전훈련된 모델을 사용하려면, RAM 사용을 최소화해야 하는 과제가 있습니다. 일반적인 PyTorch 워크플로우는 다음과 같습니다:
+
+1. 무작위 가중치로 모델을 생성합니다.
+2. 사전훈련된 가중치를 불러옵니다.
+3. 사전훈련된 가중치를 무작위 모델에 적용합니다.
+
+1단계와 2단계 모두 모델의 전체 버전을 메모리에 적재해야 하며, 대부분 문제가 없지만 모델이 기가바이트급의 용량을 차지하기 시작하면 복사본 2개가 RAM을 초과하여 메모리 부족 이슈를 야기할 수 있습니다. 더 심각한 문제는 분산 학습을 위해 `torch.distributed`를 사용하는 경우, 프로세스마다 사전훈련된 모델을 로드하고 복사본을 2개씩 RAM에 저장한다는 것입니다.
+
+
+
+무작위로 생성된 모델은 "비어 있는" (즉 그때 메모리에 있던 것으로 이뤄진) 텐서로 초기화되며 메모리 공간을 차지합니다. 초기화된 모델/파라미터의 종류에 적합한 분포(예: 정규 분포)에 따른 무작위 초기화는 가능한 한 빠르게 하기 위해 초기화되지 않은 가중치에 대해 3단계 이후에만 수행됩니다!
+
+
+
+이 안내서에서는 Transformers가 이 문제를 해결하기 위해 제공하는 솔루션을 살펴봅니다. 주의할 점은 아직 활발히 개발 중인 분야이므로 여기서 설명하는 API가 앞으로 약간 변경될 수 있다는 것입니다.
+
+## 샤딩된 체크포인트 [[sharded-checkpoints]]
+
+4.18.0 버전 이후, 10GB 이상의 공간을 차지하는 모델 체크포인트는 자동으로 작은 조각들로 샤딩됩니다. `model.save_pretrained(save_dir)`를 실행할 때 하나의 단일 체크포인트를 가지게 될 대신, 여러 부분 체크포인트(각각의 크기는 10GB 미만)와 매개변수 이름을 해당 파일에 매핑하는 인덱스가 생성됩니다.
+
+`max_shard_size` 매개변수로 샤딩 전 최대 크기를 제어할 수 있으므로, 이 예제를 위해 샤드 크기가 작은 일반 크기의 모델을 사용하겠습니다: 전통적인 BERT 모델을 사용해 봅시다.
+
+```py
+from transformers import AutoModel
+
+model = AutoModel.from_pretrained("google-bert/bert-base-cased")
+```
+
+[`~PreTrainedModel.save_pretrained`]을 사용하여 모델을 저장하면, 모델의 구성과 가중치가 들어있는 두 개의 파일이 있는 새 폴더가 생성됩니다:
+
+```py
+>>> import os
+>>> import tempfile
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir)
+... print(sorted(os.listdir(tmp_dir)))
+['config.json', 'pytorch_model.bin']
+```
+
+이제 최대 샤드 크기를 200MB로 사용해 봅시다:
+
+```py
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... print(sorted(os.listdir(tmp_dir)))
+['config.json', 'pytorch_model-00001-of-00003.bin', 'pytorch_model-00002-of-00003.bin', 'pytorch_model-00003-of-00003.bin', 'pytorch_model.bin.index.json']
+```
+
+모델의 구성에 더해, 세 개의 다른 가중치 파일과 파라미터 이름과 해당 파일의 매핑이 포함된 `index.json` 파일을 볼 수 있습니다. 이러한 체크포인트는 [`~PreTrainedModel.from_pretrained`] 메서드를 사용하여 완전히 다시 로드할 수 있습니다:
+
+```py
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... new_model = AutoModel.from_pretrained(tmp_dir)
+```
+
+큰 모델의 경우 이러한 방식으로 처리하는 주된 장점은 위에서 보여준 흐름의 2단계에서, 각 샤드가 이전 샤드 다음에 로드되므로 메모리 사용량이 모델 크기와 가장 큰 샤드의 크기를 초과하지 않는다는 점입니다.
+
+이 인덱스 파일은 키가 체크포인트에 있는지, 그리고 해당 가중치가 어디에 저장되어 있는지를 결정하는 데 사용됩니다. 이 인덱스를 json과 같이 로드하고 딕셔너리를 얻을 수 있습니다:
+
+```py
+>>> import json
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... with open(os.path.join(tmp_dir, "pytorch_model.bin.index.json"), "r") as f:
+... index = json.load(f)
+
+>>> print(index.keys())
+dict_keys(['metadata', 'weight_map'])
+```
+
+메타데이터는 현재 모델의 총 크기만 포함됩니다. 앞으로 다른 정보를 추가할 계획입니다:
+
+```py
+>>> index["metadata"]
+{'total_size': 433245184}
+```
+
+가중치 맵은 이 인덱스의 주요 부분으로, 각 매개변수 이름(PyTorch 모델 `state_dict`에서 보통 찾을 수 있는)을 해당 파일에 매핑합니다:
+
+```py
+>>> index["weight_map"]
+{'embeddings.LayerNorm.bias': 'pytorch_model-00001-of-00003.bin',
+ 'embeddings.LayerNorm.weight': 'pytorch_model-00001-of-00003.bin',
+ ...
+```
+
+만약 [`~PreTrainedModel.from_pretrained`]를 사용하지 않고 모델 내에서 이러한 샤딩된 체크포인트를 직접 가져오려면 (전체 체크포인트를 위해 `model.load_state_dict()`를 수행하는 것처럼), [`~modeling_utils.load_sharded_checkpoint`]를 사용해야 합니다.
+
+```py
+>>> from transformers.modeling_utils import load_sharded_checkpoint
+
+>>> with tempfile.TemporaryDirectory() as tmp_dir:
+... model.save_pretrained(tmp_dir, max_shard_size="200MB")
+... load_sharded_checkpoint(model, tmp_dir)
+```
+
+## 저(低)메모리 로딩 [[low-memory-loading]]
+
+샤딩된 체크포인트는 위에서 언급한 작업 흐름의 2단계에서 메모리 사용량을 줄이지만, 저(低)메모리 설정에서 모델을 사용하기 위해 우리의 Accelerate 라이브러리를 기반으로 한 도구를 활용하는 것이 좋습니다.
+
+자세한 사항은 다음 가이드를 참조해주세요: [Accelerate로 대규모 모델 가져오기 (영문)](../en/main_classes/model#large-model-loading)
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/chat_templating.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/chat_templating.md
new file mode 100644
index 0000000000000000000000000000000000000000..5e6cbc4491dd9951f42f00b8c5022e72dda920c6
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/chat_templating.md
@@ -0,0 +1,720 @@
+
+
+# 채팅 모델을 위한 템플릿[[templates-for-chat-models]]
+
+## 소개[[introduction]]
+
+요즘 LLM의 가장 흔한 활용 사례 중 하나는 **채팅**입니다. 채팅은 일반적인 언어 모델처럼 단일 문자열을 이어가는 대신 여러 개의 **메시지**로 구성된 대화를 이어갑니다. 이 대화에는 "사용자"나 "어시스턴트"와 같은 **역할**과 메시지 텍스트가 포함됩니다.
+
+토큰화와 마찬가지로, 다양한 모델은 채팅에 대해 매우 다른 입력 형식을 기대합니다. 이것이 우리가 **채팅 템플릿**을 기능으로 추가한 이유입니다. 채팅 템플릿은 토크나이저의 일부입니다. 채팅 템플릿은 대화 목록을 모델이 기대하는 형식인 '단일 토큰화가 가능한 문자열'로 변환하는 방법을 지정합니다.
+
+`BlenderBot` 모델을 사용한 간단한 예제를 통해 이를 구체적으로 살펴보겠습니다. BlenderBot은 기본적으로 매우 간단한 템플릿을 가지고 있으며, 주로 대화 라운드 사이에 공백을 추가합니다:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/blenderbot-400M-distill")
+
+>>> chat = [
+... {"role": "user", "content": "Hello, how are you?"},
+... {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+... {"role": "user", "content": "I'd like to show off how chat templating works!"},
+... ]
+
+>>> tokenizer.apply_chat_template(chat, tokenize=False)
+" Hello, how are you? I'm doing great. How can I help you today? I'd like to show off how chat templating works!"
+```
+
+전체 채팅이 하나의 문자열로 압축된 것을 확인할 수 있습니다. 기본 설정인 `tokenize=True`를 사용하면, 그 문자열도 토큰화됩니다. 더 복잡한 템플릿을 사용하기 위해 `mistralai/Mistral-7B-Instruct-v0.1` 모델을 사용해 보겠습니다.
+
+```python
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-Instruct-v0.1")
+
+>>> chat = [
+... {"role": "user", "content": "Hello, how are you?"},
+... {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+... {"role": "user", "content": "I'd like to show off how chat templating works!"},
+... ]
+
+>>> tokenizer.apply_chat_template(chat, tokenize=False)
+"[INST] Hello, how are you? [/INST]I'm doing great. How can I help you today? [INST] I'd like to show off how chat templating works! [/INST]"
+```
+
+이번에는 토크나이저가 [INST]와 [/INST] 제어 토큰을 추가하여 사용자 메시지의 시작과 끝을 표시했습니다(어시스턴트 메시지 제외). Mistral-instruct는 이러한 토큰으로 훈련되었지만, BlenderBot은 그렇지 않았습니다.
+
+## 채팅 템플릿을 어떻게 사용하나요?[[how-do-i-use-chat-templates]]
+
+위의 예에서 볼 수 있듯이 채팅 템플릿은 사용하기 쉽습니다. `role`과 `content` 키가 포함된 메시지 목록을 작성한 다음, [`~PreTrainedTokenizer.apply_chat_template`] 메서드에 전달하기만 하면 됩니다. 이렇게 하면 바로 사용할 수 있는 출력이 생성됩니다! 모델 생성의 입력으로 채팅 템플릿을 사용할 때, `add_generation_prompt=True`를 사용하여 [생성 프롬프트](#what-are-generation-prompts)를 추가하는 것도 좋은 방법입니다.
+
+다음은 `Zephyr` 어시스턴트 모델을 사용하여 `model.generate()`의 입력을 준비하는 예제입니다:
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+checkpoint = "HuggingFaceH4/zephyr-7b-beta"
+tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+model = AutoModelForCausalLM.from_pretrained(checkpoint) # 여기서 bfloat16 사용 및/또는 GPU로 이동할 수 있습니다.
+
+
+messages = [
+ {
+ "role": "system",
+ "content": "You are a friendly chatbot who always responds in the style of a pirate",
+ },
+ {"role": "user", "content": "How many helicopters can a human eat in one sitting?"},
+ ]
+tokenized_chat = tokenizer.apply_chat_template(messages, tokenize=True, add_generation_prompt=True, return_tensors="pt")
+print(tokenizer.decode(tokenized_chat[0]))
+```
+이렇게 하면 Zephyr가 기대하는 입력 형식의 문자열이 생성됩니다.
+```text
+<|system|>
+You are a friendly chatbot who always responds in the style of a pirate
+<|user|>
+How many helicopters can a human eat in one sitting?
+<|assistant|>
+```
+
+이제 입력이 Zephyr에 맞게 형식이 지정되었으므로 모델을 사용하여 사용자의 질문에 대한 응답을 생성할 수 있습니다:
+
+```python
+outputs = model.generate(tokenized_chat, max_new_tokens=128)
+print(tokenizer.decode(outputs[0]))
+```
+
+이렇게 하면 다음과 같은 결과가 나옵니다:
+
+```text
+<|system|>
+You are a friendly chatbot who always responds in the style of a pirate
+<|user|>
+How many helicopters can a human eat in one sitting?
+<|assistant|>
+Matey, I'm afraid I must inform ye that humans cannot eat helicopters. Helicopters are not food, they are flying machines. Food is meant to be eaten, like a hearty plate o' grog, a savory bowl o' stew, or a delicious loaf o' bread. But helicopters, they be for transportin' and movin' around, not for eatin'. So, I'd say none, me hearties. None at all.
+```
+
+이제 쉬워졌죠!
+
+## 채팅을 위한 자동화된 파이프라인이 있나요?[[is-there-an-automated-pipeline-for-chat]]
+
+네, 있습니다! 우리의 텍스트 생성 파이프라인은 채팅 입력을 지원하여 채팅 모델을 쉽게 사용할 수 있습니다. 이전에는 "ConversationalPipeline" 클래스를 사용했지만, 이제는 이 기능이 [`TextGenerationPipeline`]에 통합되었습니다. 이번에는 파이프라인을 사용하여 `Zephyr` 예제를 다시 시도해 보겠습니다:
+
+```python
+from transformers import pipeline
+
+pipe = pipeline("text-generation", "HuggingFaceH4/zephyr-7b-beta")
+messages = [
+ {
+ "role": "system",
+ "content": "You are a friendly chatbot who always responds in the style of a pirate",
+ },
+ {"role": "user", "content": "How many helicopters can a human eat in one sitting?"},
+]
+print(pipe(messages, max_new_tokens=128)[0]['generated_text'][-1]) # 어시스턴트의 응답을 출력합니다.
+```
+
+```text
+{'role': 'assistant', 'content': "Matey, I'm afraid I must inform ye that humans cannot eat helicopters. Helicopters are not food, they are flying machines. Food is meant to be eaten, like a hearty plate o' grog, a savory bowl o' stew, or a delicious loaf o' bread. But helicopters, they be for transportin' and movin' around, not for eatin'. So, I'd say none, me hearties. None at all."}
+```
+
+파이프라인은 토큰화와 `apply_chat_template` 호출 의 세부 사항을 모두 처리해주기 때문에, 모델에 채팅 템플릿이 있으면 파이프라인을 초기화하고 메시지 목록을 전달하기만 하면 됩니다!
+
+
+## "생성 프롬프트"란 무엇인가요?[[what-are-generation-prompts]]
+
+`apply_chat_template` 메서드에는 `add_generation_prompt` 인수가 있다는 것을 눈치챘을 것입니다. 이 인수는 템플릿에 봇 응답의 시작을 나타내는 토큰을 추가하도록 지시합니다. 예를 들어, 다음과 같은 채팅을 고려해 보세요:
+
+```python
+messages = [
+ {"role": "user", "content": "Hi there!"},
+ {"role": "assistant", "content": "Nice to meet you!"},
+ {"role": "user", "content": "Can I ask a question?"}
+]
+```
+
+Zephyr 예제에서 보았던 것과 같이, 생성 프롬프트 없이 ChatML 템플릿을 사용한다면 다음과 같이 보일 것입니다:
+
+```python
+tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=False)
+"""<|im_start|>user
+Hi there!<|im_end|>
+<|im_start|>assistant
+Nice to meet you!<|im_end|>
+<|im_start|>user
+Can I ask a question?<|im_end|>
+"""
+```
+
+생성 프롬프트가 **있는** 경우는 다음과 같습니다:
+
+```python
+tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+"""<|im_start|>user
+Hi there!<|im_end|>
+<|im_start|>assistant
+Nice to meet you!<|im_end|>
+<|im_start|>user
+Can I ask a question?<|im_end|>
+<|im_start|>assistant
+"""
+```
+
+이번에는 봇 응답의 시작을 나타내는 토큰을 추가한 것을 주목하세요. 이렇게 하면 모델이 텍스트를 생성할 때 사용자의 메시지를 계속하는 대신 봇 응답을 작성하게 됩니다. 기억하세요, 채팅 모델은 여전히 언어 모델일 뿐이며, 그들에게 채팅은 특별한 종류의 텍스트일 뿐입니다! 적절한 제어 토큰으로 안내해야 채팅 모델이 무엇을 해야 하는지 알 수 있습니다.
+
+모든 모델이 생성 프롬프트를 필요로 하는 것은 아닙니다. BlenderBot과 LLaMA 같은 일부 모델은 봇 응답 전에 특별한 토큰이 없습니다. 이러한 경우 `add_generation_prompt` 인수는 효과가 없습니다. `add_generation_prompt`의 정확한 효과는 사용 중인 템플릿에 따라 다릅니다.
+
+
+
+## 채팅 템플릿을 훈련에 사용할 수 있나요?[[can-i-use-chat-templates-in-training]]
+
+네! 이 방법은 채팅 템플릿을 모델이 훈련 중에 보는 토큰과 일치하도록 하는 좋은 방법입니다. 데이터 세트에 대한 전처리 단계로 채팅 템플릿을 적용하는 것이 좋습니다. 그 후에는 다른 언어 모델 훈련 작업과 같이 계속할 수 있습니다. 훈련할 때는 일반적으로 `add_generation_prompt=False`로 설정해야 합니다. 어시스턴트 응답을 프롬프트하는 추가 토큰은 훈련 중에는 도움이 되지 않기 때문입니다. 예제를 보겠습니다:
+
+```python
+from transformers import AutoTokenizer
+from datasets import Dataset
+
+tokenizer = AutoTokenizer.from_pretrained("HuggingFaceH4/zephyr-7b-beta")
+
+chat1 = [
+ {"role": "user", "content": "Which is bigger, the moon or the sun?"},
+ {"role": "assistant", "content": "The sun."}
+]
+chat2 = [
+ {"role": "user", "content": "Which is bigger, a virus or a bacterium?"},
+ {"role": "assistant", "content": "A bacterium."}
+]
+
+dataset = Dataset.from_dict({"chat": [chat1, chat2]})
+dataset = dataset.map(lambda x: {"formatted_chat": tokenizer.apply_chat_template(x["chat"], tokenize=False, add_generation_prompt=False)})
+print(dataset['formatted_chat'][0])
+```
+다음과 같은 결과를 얻을 수 있습니다:
+```text
+<|user|>
+Which is bigger, the moon or the sun?
+<|assistant|>
+The sun.
+```
+
+여기서부터는 일반적인 언어 모델 작업과 같이 `formatted_chat` 열을 사용하여 훈련을 계속하면 됩니다.
+
+
+`apply_chat_template(tokenize=False)`로 텍스트를 형식화한 다음 별도의 단계에서 토큰화하는 경우, `add_special_tokens=False` 인수를 설정해야 합니다. `apply_chat_template(tokenize=True)`를 사용하는 경우에는 이 문제를 걱정할 필요가 없습니다!
+기본적으로 일부 토크나이저는 토큰화할 때 `` 및 ``와 같은 특별 토큰을 추가합니다. 채팅 템플릿은 항상 필요한 모든 특별 토큰을 포함해야 하므로, 기본 `add_special_tokens=True`로 추가적인 특별 토큰을 추가하면 잘못되거나 중복되는 특별 토큰을 생성하여 모델 성능이 저하될 수 있습니다.
+
+
+## 고급: 채팅 템플릿에 추가 입력 사용[[advanced-extra-inputs-to-chat-templates]]
+
+`apply_chat_template`가 필요한 유일한 인수는 `messages`입니다. 그러나 `apply_chat_template`에 키워드 인수를 전달하면 템플릿 내부에서 사용할 수 있습니다. 이를 통해 채팅 템플릿을 다양한 용도로 사용할 수 있는 자유를 얻을 수 있습니다. 이러한 인수의 이름이나 형식에는 제한이 없어 문자열, 리스트, 딕셔너리 등을 전달할 수 있습니다.
+
+그렇긴 하지만, 이러한 추가 인수의 일반적인 사용 사례로 '함수 호출을 위한 도구'나 '검색 증강 생성을 위한 문서'를 전달하는 것이 있습니다. 이러한 일반적인 경우에 대해 인수의 이름과 형식에 대한 몇 가지 권장 사항이 있으며, 이는 아래 섹션에 설명되어 있습니다. 우리는 모델 작성자에게 도구 호출 코드를 모델 간에 쉽게 전송할 수 있도록 채팅 템플릿을 이 형식과 호환되도록 만들 것을 권장합니다.
+
+## 고급: 도구 사용 / 함수 호출[[advanced-tool-use--function-calling]]
+
+"도구 사용" LLM은 답변을 생성하기 전에 외부 도구로서 함수를 호출할 수 있습니다. 도구 사용 모델에 도구를 전달할 때는 단순히 함수 목록을 `tools` 인수로 전달할 수 있습니다:
+
+```python
+import datetime
+
+def current_time():
+ """현재 현지 시간을 문자열로 가져옵니다."""
+ return str(datetime.now())
+
+def multiply(a: float, b: float):
+ """
+ 두 숫자를 곱하는 함수
+
+ 인수:
+ a: 곱할 첫 번째 숫자
+ b: 곱할 두 번째 숫자
+ """
+ return a * b
+
+tools = [current_time, multiply]
+
+model_input = tokenizer.apply_chat_template(
+ messages,
+ tools=tools
+)
+```
+
+이것이 올바르게 작동하려면 함수를 위 형식으로 작성해야 도구로 올바르게 구문 분석할 수 있습니다. 구체적으로 다음 규칙을 따라야 합니다:
+
+- 함수는 설명적인 이름을 가져야 합니다.
+- 모든 인수에는 타입 힌트가 있어야 합니다.
+- 함수에는 표준 Google 스타일의 도크스트링이 있어야 합니다(즉, 초기 함수 설명 다음에 인수를 설명하는 `Args:` 블록이 있어야 합니다).
+- `Args:` 블록에는 타입을 포함하지 마세요. 즉, `a (int): The first number to multiply` 대신 `a: The first number to multiply`라고 작성해야 합니다. 타입 힌트는 함수 헤더에 있어야 합니다.
+- 함수에는 반환 타입과 도크스트링에 `Returns:` 블록이 있을 수 있습니다. 그러나 대부분의 도구 사용 모델은 이를 무시하므로 이는 선택 사항입니다.
+
+
+### 도구 결과를 모델에 전달하기[[passing-tool-results-to-the-model]]
+
+위의 예제 코드는 모델에 사용할 수 있는 도구를 나열하는 데 충분하지만, 실제로 사용하고자 하는 경우는 어떻게 해야 할까요? 이러한 경우에는 다음을 수행해야 합니다:
+
+1. 모델의 출력을 파싱하여 도구 이름과 인수를 가져옵니다.
+2. 모델의 도구 호출을 대화에 추가합니다.
+3. 해당 인수에 대응하는 함수를 호출합니다.
+4. 결과를 대화에 추가합니다.
+
+### 도구 사용 예제[[a-complete-tool-use-example]]
+
+도구 사용 예제를 단계별로 살펴보겠습니다. 이 예제에서는 도구 사용 모델 중에서 성능이 가장 우수한 8B `Hermes-2-Pro` 모델을 사용할 것입니다. 메모리가 충분하다면, 더 큰 모델인 [Command-R](https://huggingface.co/CohereForAI/c4ai-command-r-v01) 또는 [Mixtral-8x22B](https://huggingface.co/mistralai/Mixtral-8x22B-Instruct-v0.1)를 사용하는 것도 고려할 수 있습니다. 이 두 모델 모두 도구 사용을 지원하며 더 강력한 성능을 제공합니다.
+
+먼저 모델과 토크나이저를 로드해 보겠습니다:
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+checkpoint = "NousResearch/Hermes-2-Pro-Llama-3-8B"
+
+tokenizer = AutoTokenizer.from_pretrained(checkpoint, revision="pr/13")
+model = AutoModelForCausalLM.from_pretrained(checkpoint, torch_dtype=torch.bfloat16, device_map="auto")
+```
+
+다음으로, 도구 목록을 정의해 보겠습니다:
+
+```python
+def get_current_temperature(location: str, unit: str) -> float:
+ """
+ 특정 위치의 현재 온도를 가져옵니다.
+
+ 인수:
+ 위치: 온도를 가져올 위치, "도시, 국가" 형식
+ 단위: 온도 단위 (선택지: ["celsius", "fahrenheit"])
+ 반환값:
+ 지정된 위치의 현재 온도를 지정된 단위로 반환, float 형식.
+ """
+ return 22. # 이 함수는 실제로 온도를 가져와야 할 것입니다!
+
+def get_current_wind_speed(location: str) -> float:
+ """
+ 주어진 위치의 현재 풍속을 km/h 단위로 가져옵니다.
+
+ 인수:
+ 위치(location): 풍속을 가져올 위치, "도시, 국가" 형식
+ 반환값:
+ 주어진 위치의 현재 풍속을 km/h 단위로 반환, float 형식.
+ """
+ return 6. # 이 함수는 실제로 풍속을 가져와야 할 것입니다!
+
+tools = [get_current_temperature, get_current_wind_speed]
+```
+
+이제 봇을 위한 대화를 설정해 보겠습니다:
+
+```python
+messages = [
+ {"role": "system", "content": "You are a bot that responds to weather queries. You should reply with the unit used in the queried location."},
+ {"role": "user", "content": "Hey, what's the temperature in Paris right now?"}
+]
+```
+
+이제 채팅 템플릿을 적용하고 응답을 생성해 보겠습니다:
+
+```python
+inputs = tokenizer.apply_chat_template(messages, chat_template="tool_use", tools=tools, add_generation_prompt=True, return_dict=True, return_tensors="pt")
+inputs = {k: v.to(model.device) for k, v in inputs.items()}
+out = model.generate(**inputs, max_new_tokens=128)
+print(tokenizer.decode(out[0][len(inputs["input_ids"][0]):]))
+```
+
+결과는 다음과 같습니다:
+
+```text
+
+{"arguments": {"location": "Paris, France", "unit": "celsius"}, "name": "get_current_temperature"}
+<|im_end|>
+```
+
+모델이 함수 호출을 유효한 인수로 수행했으며, 함수 도크스트링에 요청된 형식으로 호출했음을 알 수 있습니다. 모델은 우리가 프랑스의 파리를 지칭하고 있다는 것을 추론했고, 프랑스가 SI 단위의 본고장임을 기억하여 온도를 섭씨로 표시해야 한다고 판단했습니다.
+
+모델의 도구 호출을 대화에 추가해 보겠습니다. 여기서 임의의 `tool_call_id`를 생성합니다. 이 ID는 모든 모델에서 사용되는 것은 아니지만, 여러 도구 호출을 한 번에 발행하고 각 응답이 어느 호출에 해당하는지 추적할 수 있게 해줍니다. 이 ID는 대화 내에서 고유해야 합니다.
+
+```python
+tool_call_id = "vAHdf3" # 임의의 ID, 각 도구 호출마다 고유해야 함
+tool_call = {"name": "get_current_temperature", "arguments": {"location": "Paris, France", "unit": "celsius"}}
+messages.append({"role": "assistant", "tool_calls": [{"id": tool_call_id, "type": "function", "function": tool_call}]})
+```
+
+
+이제 도구 호출을 대화에 추가했으므로, 함수를 호출하고 결과를 대화에 추가할 수 있습니다. 이 예제에서는 항상 22.0을 반환하는 더미 함수를 사용하고 있으므로, 결과를 직접 추가하면 됩니다. 다시 한 번, `tool_call_id`는 도구 호출에 사용했던 ID와 일치해야 합니다.
+
+```python
+messages.append({"role": "tool", "tool_call_id": tool_call_id, "name": "get_current_temperature", "content": "22.0"})
+```
+
+마지막으로, 어시스턴트가 함수 출력을 읽고 사용자와 계속 대화할 수 있도록 하겠습니다:
+
+```python
+inputs = tokenizer.apply_chat_template(messages, chat_template="tool_use", tools=tools, add_generation_prompt=True, return_dict=True, return_tensors="pt")
+inputs = {k: v.to(model.device) for k, v in inputs.items()}
+out = model.generate(**inputs, max_new_tokens=128)
+print(tokenizer.decode(out[0][len(inputs["input_ids"][0]):]))
+```
+
+결과는 다음과 같습니다:
+
+```text
+The current temperature in Paris, France is 22.0 ° Celsius.<|im_end|>
+```
+
+이것은 더미 도구와 단일 호출을 사용한 간단한 데모였지만, 동일한 기술을 사용하여 여러 실제 도구와 더 긴 대화를 처리할 수 있습니다. 이를 통해 실시간 정보, 계산 도구 또는 대규모 데이터베이스에 접근하여 대화형 에이전트의 기능을 확장할 수 있습니다.
+
+
+위에서 보여준 도구 호출 기능은 모든 모델에서 사용되는 것은 아닙니다. 일부 모델은 도구 호출 ID를 사용하고, 일부는 함수 이름만 사용하여 결과와 도구 호출을 순서에 따라 매칭하며, 혼동을 피하기 위해 한 번에 하나의 도구 호출만 발행하는 모델도 있습니다. 가능한 많은 모델과 호환되는 코드를 원한다면, 여기에 보여준 것처럼 도구 호출을 구성하고, 모델이 발행한 순서대로 도구 결과를 반환하는 것을 권장합니다. 각 모델의 채팅 템플릿이 나머지 작업을 처리할 것입니다.
+
+
+### 도구 스키마 이해하기[[understanding-tool-schemas]]
+
+`apply_chat_template`의 `tools` 인수에 전달하는 각 함수는 [JSON 스키마](https://json-schema.org/learn/getting-started-step-by-step)로 변환됩니다. 이러한 스키마는 모델 채팅 템플릿에 전달됩니다. 즉, 도구 사용 모델은 함수 자체를 직접 보지 않으며, 함수 내부의 실제 코드를 보지 않습니다. 도구 사용 모델이 관심을 가지는 것은 함수 **정의**와 **인수**입니다. 함수가 무엇을 하고 어떻게 사용하는지에 관심이 있을 뿐, 어떻게 작동하는지는 중요하지 않습니다! 모델의 출력을 읽고 모델이 도구 사용을 요청했는지 감지하여, 인수를 도구 함수에 전달하고 채팅에서 응답을 반환하는 것은 여러분의 몫입니다.
+
+위의 규격을 따른다면, 템플릿에 전달할 JSON 스키마 생성을 자동화하고 보이지 않게 처리하는 것이 좋습니다. 그러나 문제가 발생하거나 변환을 더 제어하고 싶다면 수동으로 변환을 처리할 수 있습니다. 다음은 수동 스키마 변환 예제입니다.
+
+```python
+from transformers.utils import get_json_schema
+
+def multiply(a: float, b: float):
+ """
+ 두 숫자를 곱하는 함수
+
+ 인수:
+ a: 곱할 첫 번째 숫자
+ b: 곱할 두 번째 숫자
+ """
+ return a * b
+
+schema = get_json_schema(multiply)
+print(schema)
+```
+
+이 결과는 다음과 같습니다:
+
+```json
+{
+ "type": "function",
+ "function": {
+ "name": "multiply",
+ "description": "A function that multiplies two numbers",
+ "parameters": {
+ "type": "object",
+ "properties": {
+ "a": {
+ "type": "number",
+ "description": "The first number to multiply"
+ },
+ "b": {
+ "type": "number",
+ "description": "The second number to multiply"
+ }
+ },
+ "required": ["a", "b"]
+ }
+ }
+}
+```
+
+원한다면 이러한 스키마를 편집하거나 `get_json_schema`를 전혀 사용하지 않고 처음부터 직접 작성할 수도 있습니다. JSON 스키마는 `apply_chat_template`의 `tools` 인수에 직접 전달할 수 있습니다. 이를 통해 더 복잡한 함수에 대한 정밀한 스키마를 정의할 수 있게 됩니다. 그러나 스키마가 복잡할수록 모델이 처리하는 데 혼란을 겪을 가능성이 높아집니다! 가능한 한 간단한 함수 서명을 유지하고, 인수(특히 복잡하고 중첩된 인수)를 최소화하는 것을 권장합니다.
+
+여기 직접 스키마를 정의하고 이를 `apply_chat_template`에 전달하는 예제가 있습니다:
+
+```python
+# 인수를 받지 않는 간단한 함수
+current_time = {
+ "type": "function",
+ "function": {
+ "name": "current_time",
+ "description": "Get the current local time as a string.",
+ "parameters": {
+ 'type': 'object',
+ 'properties': {}
+ }
+ }
+}
+
+# 두 개의 숫자 인수를 받는 더 완전한 함수
+multiply = {
+ 'type': 'function',
+ 'function': {
+ 'name': 'multiply',
+ 'description': 'A function that multiplies two numbers',
+ 'parameters': {
+ 'type': 'object',
+ 'properties': {
+ 'a': {
+ 'type': 'number',
+ 'description': 'The first number to multiply'
+ },
+ 'b': {
+ 'type': 'number', 'description': 'The second number to multiply'
+ }
+ },
+ 'required': ['a', 'b']
+ }
+ }
+}
+
+model_input = tokenizer.apply_chat_template(
+ messages,
+ tools = [current_time, multiply]
+)
+```
+
+## 고급: 검색 증강 생성[[advanced-retrieval-augmented-generation]]
+
+"검색 증강 생성" 또는 "RAG" LLM은 쿼리에 응답하기 전에 문서의 코퍼스를 검색하여 정보를 얻을 수 있습니다. 이를 통해 모델은 제한된 컨텍스트 크기 이상으로 지식 기반을 크게 확장할 수 있습니다. RAG 모델에 대한 우리의 권장 사항은 템플릿이 `documents` 인수를 허용해야 한다는 것입니다. 이 인수는 각 "문서"가 `title`과 `contents` 키를 가지는 단일 dict인 문서 목록이어야 합니다. 이 형식은 도구에 사용되는 JSON 스키마보다 훨씬 간단하므로 별도의 도우미 함수가 필요하지 않습니다.
+
+
+다음은 RAG 템플릿이 작동하는 예제입니다:
+
+
+```python
+document1 = {
+ "title": "The Moon: Our Age-Old Foe",
+ "contents": "Man has always dreamed of destroying the moon. In this essay, I shall..."
+}
+
+document2 = {
+ "title": "The Sun: Our Age-Old Friend",
+ "contents": "Although often underappreciated, the sun provides several notable benefits..."
+}
+
+model_input = tokenizer.apply_chat_template(
+ messages,
+ documents=[document1, document2]
+)
+```
+
+## 고급: 채팅 템플릿은 어떻게 작동하나요?[[advanced-how-do-chat-templates-work]]
+
+모델의 채팅 템플릿은 `tokenizer.chat_template` 속성에 저장됩니다. 채팅 템플릿이 설정되지 않은 경우 해당 모델 클래스의 기본 템플릿이 대신 사용됩니다. `BlenderBot`의 템플릿을 살펴보겠습니다:
+
+```python
+
+>>> from transformers import AutoTokenizer
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/blenderbot-400M-distill")
+
+>>> tokenizer.chat_template
+"{% for message in messages %}{% if message['role'] == 'user' %}{{ ' ' }}{% endif %}{{ message['content'] }}{% if not loop.last %}{{ ' ' }}{% endif %}{% endfor %}{{ eos_token }}"
+```
+
+약간 복잡해 보일 수 있습니다. 읽기 쉽게 정리해 보겠습니다. 이 과정에서 추가하는 줄바꿈과 들여쓰기가 템플릿 출력에 포함되지 않도록 해야 합니다. 아래는 [공백을 제거하는](#trimming-whitespace) 팁입니다:
+
+```
+{%- for message in messages %}
+ {%- if message['role'] == 'user' %}
+ {{- ' ' }}
+ {%- endif %}
+ {{- message['content'] }}
+ {%- if not loop.last %}
+ {{- ' ' }}
+ {%- endif %}
+{%- endfor %}
+{{- eos_token }}
+```
+
+만약 이와 같은 형식을 처음 본다면, 이것은 [Jinja 템플릿](https://jinja.palletsprojects.com/en/3.1.x/templates/)입니다.
+Jinja는 텍스트를 생성하는 간단한 코드를 작성할 수 있는 템플릿 언어입니다. 많은 면에서 코드와 구문이 파이썬과 유사합니다. 순수 파이썬에서는 이 템플릿이 다음과 같이 보일 것입니다:
+
+
+```python
+for idx, message in enumerate(messages):
+ if message['role'] == 'user':
+ print(' ')
+ print(message['content'])
+ if not idx == len(messages) - 1: # Check for the last message in the conversation
+ print(' ')
+print(eos_token)
+```
+
+이 템플릿은 세 가지 일을 합니다:
+1. 각 메시지에 대해, 메시지가 사용자 메시지인 경우 공백을 추가하고, 그렇지 않으면 아무것도 출력하지 않습니다.
+2. 메시지 내용을 추가합니다.
+3. 메시지가 마지막 메시지가 아닌 경우 두 개의 공백을 추가합니다. 마지막 메시지 후에는 EOS 토큰을 출력합니다.
+
+이것은 매우 간단한 템플릿입니다. 제어 토큰을 추가하지 않으며, 이후 대화에서 모델이 어떻게 동작해야 하는지 지시하는 "시스템" 메시지를 지원하지 않습니다. 하지만 Jinja는 이러한 작업을 수행할 수 있는 많은 유연성을 제공합니다! LLaMA가 입력을 형식화하는 방식과 유사한 형식의 Jinja 템플릿을 살펴보겠습니다(실제 LLaMA 템플릿은 기본 시스템 메시지 처리와 일반적인 시스템 메시지 처리를 포함하고 있습니다 - 실제 코드에서는 이 템플릿을 사용하지 마세요!).
+
+```
+{%- for message in messages %}
+ {%- if message['role'] == 'user' %}
+ {{- bos_token + '[INST] ' + message['content'] + ' [/INST]' }}
+ {%- elif message['role'] == 'system' %}
+ {{- '<>\\n' + message['content'] + '\\n<>\\n\\n' }}
+ {%- elif message['role'] == 'assistant' %}
+ {{- ' ' + message['content'] + ' ' + eos_token }}
+ {%- endif %}
+{%- endfor %}
+```
+
+이 템플릿을 잠시 살펴보면 무엇을 하는지 이해할 수 있습니다. 먼저, 각 메시지의 "role"에 따라 특정 토큰을 추가하여 누가 메시지를 보냈는지 모델에게 명확하게 알려줍니다. 또한 사용자, 어시스턴트 및 시스템 메시지는 각각 고유한 토큰으로 래핑되어 모델이 명확하게 구분할 수 있습니다.
+
+## 고급: 채팅 템플릿 추가 및 편집[[advanced-adding-and-editing-chat-templates]]
+
+### 채팅 템플릿을 어떻게 만들 수 있나요?[[how-do-i-create-a-chat-template]]
+
+간단합니다. Jinja 템플릿을 작성하고 `tokenizer.chat_template`에 설정하기만 하면 됩니다. 다른 모델의 기존 템플릿을 시작점으로 사용하고 필요에 맞게 편집하는 것이 더 쉬울 것 입니다! 예를 들어, 위의 LLaMA 템플릿을 가져와 어시스턴트 메시지에 "[ASST]" 및 "[/ASST]"를 추가할 수 있습니다:
+
+```
+{%- for message in messages %}
+ {%- if message['role'] == 'user' %}
+ {{- bos_token + '[INST] ' + message['content'].strip() + ' [/INST]' }}
+ {%- elif message['role'] == 'system' %}
+ {{- '<>\\n' + message['content'].strip() + '\\n<>\\n\\n' }}
+ {%- elif message['role'] == 'assistant' %}
+ {{- '[ASST] ' + message['content'] + ' [/ASST]' + eos_token }}
+ {%- endif %}
+{%- endfor %}
+```
+
+이제 `tokenizer.chat_template` 속성을 설정하기만 하면 됩니다. 이렇게 하면 다음에 [`~PreTrainedTokenizer.apply_chat_template`]를 사용할 때 새롭게 설정한 템플릿이 사용됩니다! 이 속성은 `tokenizer_config.json` 파일에 저장되므로, [`~utils.PushToHubMixin.push_to_hub`]를 사용하여 새 템플릿을 허브에 업로드하고 모든 사용자가 모델에 맞는 템플릿을 사용할 수 있도록 할 수 있습니다!
+
+```python
+template = tokenizer.chat_template
+template = template.replace("SYS", "SYSTEM") # 시스템 토큰 변경
+tokenizer.chat_template = template # 새 템플릿 설정
+tokenizer.push_to_hub("model_name") # 새 템플릿을 허브에 업로드!
+```
+
+채팅 템플릿을 사용하는 [`~PreTrainedTokenizer.apply_chat_template`] 메소드는 [`TextGenerationPipeline`] 클래스에서 호출되므로, 올바른 채팅 템플릿을 설정하면 모델이 자동으로 [`TextGenerationPipeline`]과 호환됩니다.
+
+
+모델을 채팅 용도로 미세 조정하는 경우, 채팅 템플릿을 설정하는 것 외에도 새 채팅 제어 토큰을 토크나이저에 특별 토큰으로 추가하는 것이 좋습니다. 특별 토큰은 절대로 분할되지 않으므로, 제어 토큰이 여러 조각으로 토큰화되는 것을 방지합니다. 또한, 템플릿에서 어시스턴트 생성의 끝을 나타내는 토큰으로 토크나이저의 `eos_token` 속성을 설정해야 합니다. 이렇게 하면 텍스트 생성 도구가 텍스트 생성을 언제 중지해야 할지 정확히 알 수 있습니다.
+
+
+
+### 왜 일부 모델은 여러 개의 템플릿을 가지고 있나요?[[why-do-some-models-have-multiple-templates]]
+
+일부 모델은 다른 사용 사례에 대해 다른 템플릿을 사용합니다. 예를 들어, 일반 채팅을 위한 템플릿과 도구 사용 또는 검색 증강 생성에 대한 템플릿을 별도로 사용할 수 있습니다. 이러한 경우 `tokenizer.chat_template`는 딕셔너리입니다. 이것은 약간의 혼란을 초래할 수 있으며, 가능한 한 모든 사용 사례에 대해 단일 템플릿을 사용하는 것을 권장합니다. `if tools is defined`와 같은 Jinja 문장과 `{% macro %}` 정의를 사용하여 여러 코드 경로를 단일 템플릿에 쉽게 래핑할 수 있습니다.
+
+토크나이저에 여러 개의 템플릿이 있는 경우, `tokenizer.chat_template`는 템플릿 이름이 키인 `딕셔너리`입니다. `apply_chat_template` 메소드는 특정 템플릿 이름에 대한 특별한 처리를 합니다: 일반적으로 `default`라는 템플릿을 찾고, 찾을 수 없으면 오류를 발생시킵니다. 그러나 사용자가 `tools` 인수를 전달할 때 `tool_use`라는 템플릿이 존재하면 대신 그것을 사용합니다. 다른 이름의 템플릿에 접근하려면 `apply_chat_template()`의 `chat_template` 인수에 원하는 템플릿 이름을 전달하면 됩니다.
+
+사용자에게 약간의 혼란을 줄 수 있으므로, 템플릿을 직접 작성하는 경우 가능한 한 단일 템플릿에 모든 것을 넣는 것을 권장합니다!
+
+### 어떤 템플릿을 사용해야 하나요?[[what-template-should-i-use]]
+
+이미 채팅용으로 훈련된 모델에 템플릿을 설정할 때는 템플릿이 훈련 중 모델이 본 메시지 형식과 정확히 일치하도록 해야 합니다. 그렇지 않으면 성능 저하를 경험할 가능성이 큽니다. 이는 모델을 추가로 훈련할 때도 마찬가지입니다. 채팅 토큰을 일정하게 유지하는 것이 최상의 성능을 얻는 방법입니다. 이는 토큰화와 매우 유사합니다. 훈련 중에 사용된 토큰화를 정확히 일치시킬 때 추론이나 미세 조정에서 최고의 성능을 얻을 수 있습니다.
+
+반면에 처음부터 모델을 훈련시키거나 채팅용으로 기본 언어 모델을 미세 조정하는 경우, 적절한 템플릿을 선택할 수 있는 많은 자유가 있습니다. LLM은 다양한 입력 형식을 처리할 만큼 충분히 똑똑합니다. 인기 있는 선택 중 하나는 `ChatML` 형식이며, 이는 많은 사용 사례에 유연하게 사용할 수 있는 좋은 선택입니다. 다음과 같습니다:
+
+```
+{%- for message in messages %}
+ {{- '<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n' }}
+{%- endfor %}
+```
+
+이 템플릿이 마음에 든다면, 코드에 바로 복사하여 사용할 수 있는 한 줄 버전을 제공하겠습니다. 이 한 줄 버전은 [생성 프롬프트](#what-are-generation-prompts)에 대한 편리한 지원도 포함하고 있지만, BOS나 EOS 토큰을 추가하지 않는다는 점에 유의하세요! 모델이 해당 토큰을 기대하더라도, `apply_chat_template`에 의해 자동으로 추가되지 않습니다. 즉, 텍스트는 `add_special_tokens=False`에 의해 토큰화됩니다. 이는 템플릿과 `add_special_tokens` 논리 간의 잠재적인 충돌을 피하기 위함입니다. 모델이 특별 토큰을 기대하는 경우, 템플릿에 직접 추가해야 합니다!
+
+
+```python
+tokenizer.chat_template = "{% if not add_generation_prompt is defined %}{% set add_generation_prompt = false %}{% endif %}{% for message in messages %}{{'<|im_start|>' + message['role'] + '\n' + message['content'] + '<|im_end|>' + '\n'}}{% endfor %}{% if add_generation_prompt %}{{ '<|im_start|>assistant\n' }}{% endif %}"
+```
+
+이 템플릿은 각 메시지를 `<|im_start|>` 와 `<|im_end|>`토큰으로 감싸고, 역할을 문자열로 작성하여 훈련 시 사용하는 역할에 대한 유연성을 제공합니다. 출력은 다음과 같습니다:
+
+
+```text
+<|im_start|>system
+You are a helpful chatbot that will do its best not to say anything so stupid that people tweet about it.<|im_end|>
+<|im_start|>user
+How are you?<|im_end|>
+<|im_start|>assistant
+I'm doing great!<|im_end|>
+```
+
+"사용자", "시스템" 및 "어시스턴트" 역할은 채팅의 표준이며, 가능할 때 이를 사용하는 것을 권장합니다. 특히 모델이 [`TextGenerationPipeline`]과 잘 작동하도록 하려면 그렇습니다. 그러나 이러한 역할에만 국한되지 않습니다. 템플릿은 매우 유연하며, 어떤 문자열이든 역할로 사용할 수 있습니다.
+
+
+
+### 채팅 템플릿을 추가하고 싶습니다! 어떻게 시작해야 하나요?[[i-want-to-add-some-chat-templates-how-should-i-get-started]]
+
+채팅 모델이 있는 경우, 해당 모델의 `tokenizer.chat_template` 속성을 설정하고 [`~PreTrainedTokenizer.apply_chat_template`]를 사용하여 테스트한 다음 업데이트된 토크나이저를 허브에 푸시해야 합니다. 이는 모델 소유자가 아닌 경우에도 적용됩니다. 빈 채팅 템플릿을 사용하는 모델이나 여전히 기본 클래스 템플릿을 사용하는 모델을 사용하는 경우, [풀 리퀘스트](https://huggingface.co/docs/hub/repositories-pull-requests-discussions)를 모델 리포지토리에 열어 이 속성을 올바르게 설정할 수 있도록 하세요!
+
+속성을 설정하면 끝입니다! `tokenizer.apply_chat_template`가 이제 해당 모델에 대해 올바르게 작동하므로, `TextGenerationPipeline`과 같은 곳에서도 자동으로 지원됩니다!
+
+모델에 이 속성을 설정함으로써, 오픈 소스 모델의 전체 기능을 커뮤니티가 사용할 수 있도록 할 수 있습니다. 형식 불일치는 이 분야에서 오랫동안 성능을 저하시키는 문제였으므로, 이제 이를 끝낼 때입니다!
+
+## 고급: 템플릿 작성 팁[[advanced-template-writing-tips]]
+
+Jinja에 익숙하지 않은 경우, 채팅 템플릿을 작성하는 가장 쉬운 방법은 먼저 메시지를 원하는 방식으로 형식화하는 짧은 파이썬 스크립트를 작성한 다음, 해당 스크립트를 템플릿으로 변환하는 것입니다.
+
+템플릿 핸들러는 `messages`라는 변수로 대화 기록을 받습니다. 파이썬에서와 마찬가지로 템플릿 내의 `messages`에 접근할 수 있으며, `{% for message in messages %}`로 반복하거나 `{{ messages[0] }}`와 같이 개별 메시지에 접근할 수 있습니다.
+
+다음 팁을 사용하여 코드를 Jinja로 변환할 수도 있습니다:
+
+### 공백 제거[[trimming-whitespace]]
+
+기본적으로 Jinja는 블록 전후의 공백을 출력합니다. 이는 일반적으로 공백을 매우 정확하게 다루고자 하는 채팅 템플릿에서는 문제가 될 수 있습니다! 이를 피하기 위해 템플릿을 다음과 같이 작성하는 것이 좋습니다:
+
+```
+{%- for message in messages %}
+ {{- message['role'] + message['content'] }}
+{%- endfor %}
+```
+
+아래와 같이 작성하지 마세요:
+
+```
+{% for message in messages %}
+ {{ message['role'] + message['content'] }}
+{% endfor %}
+```
+
+`-`를 추가하면 블록 전후의 공백이 제거됩니다. 두 번째 예제는 무해해 보이지만, 줄바꿈과 들여쓰기가 출력에 포함될 수 있으며, 이는 원하지 않는 결과일 수 있습니다!
+
+### 반복문[[for-loops]]
+
+Jinja에서 반복문은 다음과 같습니다:
+
+```
+{%- for message in messages %}
+ {{- message['content'] }}
+{%- endfor %}
+```
+
+{{ 표현식 블록 }} 내부에 있는 모든 것이 출력으로 인쇄됩니다. `+`와 같은 연산자를 사용하여 표현식 블록 내부에서 문자열을 결합할 수 있습니다.
+
+### 조건문[[if-statements]]
+
+Jinja에서 조건문은 다음과 같습니다:
+
+```
+{%- if message['role'] == 'user' %}
+ {{- message['content'] }}
+{%- endif %}
+```
+
+파이썬이 공백을 사용하여 `for` 및 `if` 블록의 시작과 끝을 표시하는 반면, Jinja는 `{% endfor %}` 및 `{% endif %}`로 명시적으로 끝을 표시해야 합니다.
+
+### 특수 변수[[special-variables]]
+
+템플릿 내부에서는 `messages` 목록에 접근할 수 있을 뿐만 아니라 여러 다른 특수 변수에도 접근할 수 있습니다. 여기에는 `bos_token` 및 `eos_token`과 같은 특별 토큰과 앞서 논의한 `add_generation_prompt` 변수가 포함됩니다. 또한 `loop` 변수를 사용하여 현재 반복에 대한 정보를 얻을 수 있으며, 예를 들어 `{% if loop.last %}`를 사용하여 현재 메시지가 대화의 마지막 메시지인지 확인할 수 있습니다. `add_generation_prompt`가 `True`인 경우 대화 끝에 생성 프롬프트를 추가하는 예제는 다음과 같습니다:
+
+```
+{%- if loop.last and add_generation_prompt %}
+ {{- bos_token + 'Assistant:\n' }}
+{%- endif %}
+```
+
+### 비파이썬 Jinja와의 호환성[[compatibility-with-non-python-jinja]]
+
+Jinja의 여러 구현은 다양한 언어로 제공됩니다. 일반적으로 동일한 구문을 사용하지만, 주요 차이점은 파이썬에서 템플릿을 작성할 때 파이썬 메소드를 사용할 수 있다는 점입니다. 예를 들어, 문자열에 `.lower()`를 사용하거나 딕셔너리에 `.items()`를 사용하는 것입니다. 이는 비파이썬 Jinja 구현에서 템플릿을 사용하려고 할 때 문제가 발생할 수 있습니다. 특히 JS와 Rust가 인기 있는 배포 환경에서는 비파이썬 구현이 흔합니다.
+
+하지만 걱정하지 마세요! 모든 Jinja 구현에서 호환성을 보장하기 위해 템플릿을 쉽게 변경할 수 있는 몇 가지 방법이 있습니다:
+
+- 파이썬 메소드를 Jinja 필터로 대체하세요. 일반적으로 같은 이름을 가지며, 예를 들어 `string.lower()`는 `string|lower`로, `dict.items()`는 `dict|items`로 대체할 수 있습니다. 주목할 만한 변경 사항은 `string.strip()`이 `string|trim`으로 바뀌는 것입니다. 더 자세한 내용은 Jinja 문서의 [내장 필터 목록](https://jinja.palletsprojects.com/en/3.1.x/templates/#builtin-filters)을 참조하세요.
+- 파이썬에 특화된 `True`, `False`, `None`을 각각 `true`, `false`, `none`으로 대체하세요.
+- 딕셔너리나 리스트를 직접 렌더링할 때 다른 구현에서는 결과가 다를 수 있습니다(예: 문자열 항목이 단일 따옴표에서 이중 따옴표로 변경될 수 있습니다). `tojson` 필터를 추가하면 일관성을 유지하는 데 도움이 됩니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/community.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/community.md
new file mode 100644
index 0000000000000000000000000000000000000000..d50168d7548620805d06b2aa06190bbbc8d4d936
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/community.md
@@ -0,0 +1,69 @@
+
+
+# 커뮤니티 [[community]]
+
+이 페이지는 커뮤니티에서 개발한 🤗 Transformers 리소스를 재구성한 페이지입니다.
+
+## 커뮤니티 리소스: [[community-resources]]
+
+| 리소스 | 설명 | 만든이 |
+|:----------|:-------------|------:|
+| [Hugging Face Transformers 용어집 플래시카드](https://www.darigovresearch.com/huggingface-transformers-glossary-flashcards) | [Transformers 문서 용어집](glossary)을 기반으로 한 플래시카드 세트로, 지식을 장기적으로 유지하기 위해 특별히 설계된 오픈소스 크로스 플랫폼 앱인 [Anki](https://apps.ankiweb.net/)를 사용하여 쉽게 학습/수정할 수 있는 형태로 제작되었습니다. [플래시카드 사용법에 대한 소개 동영상](https://www.youtube.com/watch?v=Dji_h7PILrw)을 참조하세요. | [Darigov 리서치](https://www.darigovresearch.com/) |
+
+## 커뮤니티 노트북: [[community-notebooks]]
+
+| 노트북 | 설명 | 만든이 | |
+|:----------|:-------------|:-------------|------:|
+| [가사를 생성하기 위해 사전훈련된 트랜스포머를 미세 조정하기](https://github.com/AlekseyKorshuk/huggingartists) | GPT-2 모델을 미세 조정하여 좋아하는 아티스트의 스타일로 가사를 생성하는 방법 | [Aleksey Korshuk](https://github.com/AlekseyKorshuk) | [](https://colab.research.google.com/github/AlekseyKorshuk/huggingartists/blob/master/huggingartists-demo.ipynb) |
+| [Tensorflow 2로 T5 훈련하기](https://github.com/snapthat/TF-T5-text-to-text) | Tensorflow 2를 사용하여 T5를 훈련시키는 방법. 이 노트북은 Tensorflow 2로 SQUAD를 사용하여 구현한 질의응답 작업을 보여줍니다. | [Muhammad Harris](https://github.com/HarrisDePerceptron) |[](https://colab.research.google.com/github/snapthat/TF-T5-text-to-text/blob/master/snapthatT5/notebooks/TF-T5-Datasets%20Training.ipynb) |
+| [TPU에서 T5 훈련하기](https://github.com/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb) | Transformers와 Nlp를 사용하여 SQUAD로 T5를 훈련하는 방법 | [Suraj Patil](https://github.com/patil-suraj) |[](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/T5_on_TPU.ipynb#scrollTo=QLGiFCDqvuil) |
+| [분류 및 객관식 문제를 위해 T5 미세 조정하기](https://github.com/patil-suraj/exploring-T5/blob/master/t5_fine_tuning.ipynb) | 분류 및 객관식 문제에 맞게 텍스트-텍스트 형식을 사용하여 PyTorch Lightning으로 T5를 미세 조정하는 방법 | [Suraj Patil](https://github.com/patil-suraj) | [](https://colab.research.google.com/github/patil-suraj/exploring-T5/blob/master/t5_fine_tuning.ipynb) |
+| [새로운 데이터 세트와 언어로 DialoGPT 미세 조정하기](https://github.com/ncoop57/i-am-a-nerd/blob/master/_notebooks/2020-05-12-chatbot-part-1.ipynb) | 자유 대화형 챗봇을 만들기 위해 새로운 데이터 세트로 DialoGPT 모델을 미세 조정하는 방법 | [Nathan Cooper](https://github.com/ncoop57) | [](https://colab.research.google.com/github/ncoop57/i-am-a-nerd/blob/master/_notebooks/2020-05-12-chatbot-part-1.ipynb) |
+| [Reformer로 긴 시퀀스 모델링하기](https://github.com/patrickvonplaten/notebooks/blob/master/PyTorch_Reformer.ipynb) | Reformer로 최대 50만 토큰의 시퀀스를 훈련하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/PyTorch_Reformer.ipynb) |
+| [요약을 위해 BART 미세 조정하기](https://github.com/ohmeow/ohmeow_website/blob/master/posts/2021-05-25-mbart-sequence-classification-with-blurr.ipynb) | blurr를 사용하여 fastai로 요약하기 위해 BART를 미세 조정하는 방법 | [Wayde Gilliam](https://ohmeow.com/) | [](https://colab.research.google.com/github/ohmeow/ohmeow_website/blob/master/posts/2021-05-25-mbart-sequence-classification-with-blurr.ipynb) |
+| [다른 사람의 트윗으로 사전훈련된 트랜스포머 미세 조정하기](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb) | GPT-2 모델을 미세 조정하여 좋아하는 트위터 계정 스타일로 트윗을 생성하는 방법 | [Boris Dayma](https://github.com/borisdayma) | [](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb) |
+| [Weights & Biases로 🤗 Hugging Face 모델 최적화하기](https://colab.research.google.com/github/wandb/examples/blob/master/colabs/huggingface/Optimize_Hugging_Face_models_with_Weights_%26_Biases.ipynb) | W&B와 Hugging Face의 통합을 보여주는 전체 튜토리얼 | [Boris Dayma](https://github.com/borisdayma) | [](https://colab.research.google.com/github/wandb/examples/blob/master/colabs/huggingface/Optimize_Hugging_Face_models_with_Weights_%26_Biases.ipynb) |
+| [Longformer 사전훈련하기](https://github.com/allenai/longformer/blob/master/scripts/convert_model_to_long.ipynb) | 기존 사전훈련된 모델의 "긴" 버전을 빌드하는 방법 | [Iz Beltagy](https://beltagy.net) | [](https://colab.research.google.com/github/allenai/longformer/blob/master/scripts/convert_model_to_long.ipynb) |
+| [QA를 위해 Longformer 미세 조정하기](https://github.com/patil-suraj/Notebooks/blob/master/longformer_qa_training.ipynb) | QA 작업을 위해 Longformer를 미세 조정하는 방법 | [Suraj Patil](https://github.com/patil-suraj) | [](https://colab.research.google.com/github/patil-suraj/Notebooks/blob/master/longformer_qa_training.ipynb) |
+| [🤗 Nlp로 모델 평가하기](https://github.com/patrickvonplaten/notebooks/blob/master/How_to_evaluate_Longformer_on_TriviaQA_using_NLP.ipynb) | `Nlp`로 TriviaQA에서 Longformer를 평가하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/drive/1m7eTGlPmLRgoPkkA7rkhQdZ9ydpmsdLE?usp=sharing) |
+| [감정 범위 추출을 위해 T5 미세 조정하기](https://github.com/enzoampil/t5-intro/blob/master/t5_qa_training_pytorch_span_extraction.ipynb) | 감정 범위 추출을 위해 텍스트-텍스트 형식을 사용하여 PyTorch Lightning으로 T5를 미세 조정하는 방법 | [Lorenzo Ampil](https://github.com/enzoampil) | [](https://colab.research.google.com/github/enzoampil/t5-intro/blob/master/t5_qa_training_pytorch_span_extraction.ipynb) |
+| [다중 클래스 분류를 위해 DistilBert 미세 조정하기](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_multiclass_classification.ipynb) | 다중 클래스 분류를 위해 PyTorch를 사용하여 DistilBert를 미세 조정하는 방법 | [Abhishek Kumar Mishra](https://github.com/abhimishra91) | [](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_multiclass_classification.ipynb)|
+| [다중 레이블 분류를 위해 BERT 미세 조정하기](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_multi_label_classification.ipynb) | 다중 레이블 분류를 위해 PyTorch를 사용하여 BERT를 미세 조정하는 방법 | [Abhishek Kumar Mishra](https://github.com/abhimishra91) | [](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_multi_label_classification.ipynb)|
+| [요약을 위해 T5 미세 조정하기](https://github.com/abhimishra91/transformers-tutorials/blob/master/transformers_summarization_wandb.ipynb) | 요약을 위해 PyTorch로 T5를 미세 조정하고 WandB로 실험을 추적하는 방법 | [Abhishek Kumar Mishra](https://github.com/abhimishra91) | [](https://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_summarization_wandb.ipynb)|
+| [동적 패딩/버켓팅으로 Transformers 미세 조정 속도 높이기](https://github.com/ELS-RD/transformers-notebook/blob/master/Divide_Hugging_Face_Transformers_training_time_by_2_or_more.ipynb)| 동적 패딩/버켓팅을 사용하여 미세 조정 속도를 2배로 높이는 방법 |[Michael Benesty](https://github.com/pommedeterresautee) |[](https://colab.research.google.com/drive/1CBfRU1zbfu7-ijiOqAAQUA-RJaxfcJoO?usp=sharing)|
+|[마스킹된 언어 모델링을 위해 Reformer 사전훈련하기](https://github.com/patrickvonplaten/notebooks/blob/master/Reformer_For_Masked_LM.ipynb)| 양방향 셀프 어텐션 레이어를 이용해서 Reformer 모델을 훈련하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/drive/1tzzh0i8PgDQGV3SMFUGxM7_gGae3K-uW?usp=sharing)|
+| [Sci-BERT 확장 및 미세 조정하기](https://github.com/lordtt13/word-embeddings/blob/master/COVID-19%20Research%20Data/COVID-SciBERT.ipynb)| CORD 데이터 세트로 AllenAI에서 사전훈련된 SciBERT 모델의 어휘를 늘리고 파이프라인을 구축하는 방법 | [Tanmay Thakur](https://github.com/lordtt13) | [](https://colab.research.google.com/drive/1rqAR40goxbAfez1xvF3hBJphSCsvXmh8)|
+| [요약을 위해 Trainer API로 BlenderBotSmall 미세 조정하기](https://github.com/lordtt13/transformers-experiments/blob/master/Custom%20Tasks/fine-tune-blenderbot_small-for-summarization.ipynb)| 요약을 위해 Trainer API를 사용하여 사용자 지정 데이터 세트로 BlenderBotSmall 미세 조정하기 | [Tanmay Thakur](https://github.com/lordtt13) | [](https://colab.research.google.com/drive/19Wmupuls7mykSGyRN_Qo6lPQhgp56ymq?usp=sharing)|
+| [통합 기울기(Integrated Gradient)를 이용하여 Electra 미세 조정하고 해석하기](https://github.com/elsanns/xai-nlp-notebooks/blob/master/electra_fine_tune_interpret_captum_ig.ipynb) | 감정 분석을 위해 Electra를 미세 조정하고 Captum 통합 기울기로 예측을 해석하는 방법 | [Eliza Szczechla](https://elsanns.github.io) | [](https://colab.research.google.com/github/elsanns/xai-nlp-notebooks/blob/master/electra_fine_tune_interpret_captum_ig.ipynb)|
+| [Trainer 클래스로 비영어권 GPT-2 모델 미세 조정하기](https://github.com/philschmid/fine-tune-GPT-2/blob/master/Fine_tune_a_non_English_GPT_2_Model_with_Huggingface.ipynb) | Trainer 클래스로 비영어권 GPT-2 모델을 미세 조정하는 방법 | [Philipp Schmid](https://www.philschmid.de) | [](https://colab.research.google.com/github/philschmid/fine-tune-GPT-2/blob/master/Fine_tune_a_non_English_GPT_2_Model_with_Huggingface.ipynb)|
+|[다중 라벨 분류 작업을 위해 DistilBERT 모델 미세 조정하기](https://github.com/DhavalTaunk08/Transformers_scripts/blob/master/Transformers_multilabel_distilbert.ipynb) | 다중 라벨 분류 작업을 위해 DistilBERT 모델을 미세 조정하는 방법 | [Dhaval Taunk](https://github.com/DhavalTaunk08) | [](https://colab.research.google.com/github/DhavalTaunk08/Transformers_scripts/blob/master/Transformers_multilabel_distilbert.ipynb)|
+|[문장쌍 분류를 위해 ALBERT 미세 조정하기](https://github.com/NadirEM/nlp-notebooks/blob/master/Fine_tune_ALBERT_sentence_pair_classification.ipynb) | 문장쌍 분류 작업을 위해 ALBERT 모델 또는 다른 BERT 기반 모델을 미세 조정하는 방법 | [Nadir El Manouzi](https://github.com/NadirEM) | [](https://colab.research.google.com/github/NadirEM/nlp-notebooks/blob/master/Fine_tune_ALBERT_sentence_pair_classification.ipynb)|
+|[감정 분석을 위해 Roberta 미세 조정하기](https://github.com/DhavalTaunk08/NLP_scripts/blob/master/sentiment_analysis_using_roberta.ipynb) | 감정 분석을 위해 Roberta 모델을 미세 조정하는 방법 | [Dhaval Taunk](https://github.com/DhavalTaunk08) | [](https://colab.research.google.com/github/DhavalTaunk08/NLP_scripts/blob/master/sentiment_analysis_using_roberta.ipynb)|
+|[질문 생성 모델 평가하기](https://github.com/flexudy-pipe/qugeev) | seq2seq 트랜스포머 모델이 생성한 질문과 이에 대한 답변이 얼마나 정확한가요? | [Pascal Zoleko](https://github.com/zolekode) | [](https://colab.research.google.com/drive/1bpsSqCQU-iw_5nNoRm_crPq6FRuJthq_?usp=sharing)|
+|[DistilBERT와 Tensorflow로 텍스트 분류하기](https://github.com/peterbayerle/huggingface_notebook/blob/main/distilbert_tf.ipynb) | 텍스트 분류를 위해 TensorFlow로 DistilBERT를 미세 조정하는 방법 | [Peter Bayerle](https://github.com/peterbayerle) | [](https://colab.research.google.com/github/peterbayerle/huggingface_notebook/blob/main/distilbert_tf.ipynb)|
+|[CNN/Dailail 요약을 위해 인코더-디코더 모델에 BERT 활용하기](https://github.com/patrickvonplaten/notebooks/blob/master/BERT2BERT_for_CNN_Dailymail.ipynb) | CNN/Dailail 요약을 위해 *google-bert/bert-base-uncased* 체크포인트를 활용하여 *EncoderDecoderModel*을 워밍업하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/BERT2BERT_for_CNN_Dailymail.ipynb)|
+|[BBC XSum 요약을 위해 인코더-디코더 모델에 RoBERTa 활용하기](https://github.com/patrickvonplaten/notebooks/blob/master/RoBERTaShared_for_BBC_XSum.ipynb) | BBC/XSum 요약을 위해 *FacebookAI/roberta-base* 체크포인트를 활용하여 공유 *EncoderDecoderModel*을 워밍업하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/RoBERTaShared_for_BBC_XSum.ipynb)|
+|[순차적 질문 답변(SQA)을 위해 TAPAS 미세 조정하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) | *tapas-base* 체크포인트를 활용하여 순차적 질문 답변(SQA) 데이터 세트로 *TapasForQuestionAnswering*을 미세 조정하는 방법 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb)|
+|[표 사실 검사(TabFact)로 TAPAS 평가하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Evaluating_TAPAS_on_the_Tabfact_test_set.ipynb) | 🤗 Datasets와 🤗 Transformer 라이브러리를 함께 사용하여 *tapas-base-finetuned-tabfact* 체크포인트로 미세 조정된 *TapasForSequenceClassification*을 평가하는 방법 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Evaluating_TAPAS_on_the_Tabfact_test_set.ipynb)|
+|[번역을 위해 mBART 미세 조정하기](https://colab.research.google.com/github/vasudevgupta7/huggingface-tutorials/blob/main/translation_training.ipynb) | 힌디어에서 영어로 번역하기 위해 Seq2SeqTrainer를 사용하여 mBART를 미세 조정하는 방법 | [Vasudev Gupta](https://github.com/vasudevgupta7) | [](https://colab.research.google.com/github/vasudevgupta7/huggingface-tutorials/blob/main/translation_training.ipynb)|
+|[FUNSD(양식 이해 데이터 세트)로 LayoutLM 미세 조정하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb) | 스캔한 문서에서 정보 추출을 위해 FUNSD 데이터 세트로 *LayoutLMForTokenClassification*을 미세 조정하는 방법 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb)|
+|[DistilGPT2 미세 조정하고 및 텍스트 생성하기](https://colab.research.google.com/github/tripathiaakash/DistilGPT2-Tutorial/blob/main/distilgpt2_fine_tuning.ipynb) | DistilGPT2를 미세 조정하고 텍스트를 생성하는 방법 | [Aakash Tripathi](https://github.com/tripathiaakash) | [](https://colab.research.google.com/github/tripathiaakash/DistilGPT2-Tutorial/blob/main/distilgpt2_fine_tuning.ipynb)|
+|[최대 8K 토큰에서 LED 미세 조정하기](https://github.com/patrickvonplaten/notebooks/blob/master/Fine_tune_Longformer_Encoder_Decoder_(LED)_for_Summarization_on_pubmed.ipynb) | 긴 범위를 요약하기 위해 PubMed로 LED를 미세 조정하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/Fine_tune_Longformer_Encoder_Decoder_(LED)_for_Summarization_on_pubmed.ipynb)|
+|[Arxiv로 LED 평가하기](https://github.com/patrickvonplaten/notebooks/blob/master/LED_on_Arxiv.ipynb) | 긴 범위 요약에 대해 LED를 효과적으로 평가하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/LED_on_Arxiv.ipynb)|
+|[RVL-CDIP(문서 이미지 분류 데이터 세트)로 LayoutLM 미세 조정하기)](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb) | 스캔 문서 분류를 위해 RVL-CDIP 데이터 세트로 *LayoutLMForSequenceClassification*을 미세 조정하는 방법 | [Niels Rogge](https://github.com/nielsrogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb)|
+|[GPT2 조정을 통한 Wav2Vec2 CTC 디코딩](https://github.com/voidful/huggingface_notebook/blob/main/xlsr_gpt.ipynb) | 언어 모델 조정을 통해 CTC 시퀀스를 디코딩하는 방법 | [Eric Lam](https://github.com/voidful) | [](https://colab.research.google.com/drive/1e_z5jQHYbO2YKEaUgzb1ww1WwiAyydAj?usp=sharing)|
+|[Trainer 클래스로 두 개 언어로 요약하기 위해 BART 미세 조정하기](https://github.com/elsanns/xai-nlp-notebooks/blob/master/fine_tune_bart_summarization_two_langs.ipynb) | Trainer 클래스로 두 개 언어로 요약하기 위해 BART 미세 조정하는 방법 | [Eliza Szczechla](https://github.com/elsanns) | [](https://colab.research.google.com/github/elsanns/xai-nlp-notebooks/blob/master/fine_tune_bart_summarization_two_langs.ipynb)|
+|[Trivia QA로 Big Bird 평가하기](https://github.com/patrickvonplaten/notebooks/blob/master/Evaluating_Big_Bird_on_TriviaQA.ipynb) | Trivia QA로 긴 문서 질문에 대한 답변에 대해 BigBird를 평가하는 방법 | [Patrick von Platen](https://github.com/patrickvonplaten) | [](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/Evaluating_Big_Bird_on_TriviaQA.ipynb)|
+| [Wav2Vec2를 사용하여 동영상 캡션 만들기](https://github.com/Muennighoff/ytclipcc/blob/main/wav2vec_youtube_captions.ipynb) | Wav2Vec으로 오디오를 텍스트로 변환하여 모든 동영상에서 YouTube 캡션 만드는 방법 | [Niklas Muennighoff](https://github.com/Muennighoff) |[](https://colab.research.google.com/github/Muennighoff/ytclipcc/blob/main/wav2vec_youtube_captions.ipynb) |
+| [PyTorch Lightning을 사용하여 CIFAR-10으로 비전 트랜스포머 미세 조정하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_PyTorch_Lightning.ipynb) | HuggingFace Transformers, Datasets, PyTorch Lightning을 사용하여 CIFAR-10으로 비전 트랜스포머(ViT)를 미세 조정하는 방법 | [Niels Rogge](https://github.com/nielsrogge) |[](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_PyTorch_Lightning.ipynb) |
+| [🤗 Trainer를 사용하여 CIFAR-10에서 비전 트랜스포머 미세 조정하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_the_%F0%9F%A4%97_Trainer.ipynb) | Datasets, 🤗 Trainer를 사용하여 CIFAR-10에서 비전 트랜스포머(ViT)를 미세 조정하는 방법 | [Niels Rogge](https://github.com/nielsrogge) |[](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_the_%F0%9F%A4%97_Trainer.ipynb) |
+| [개체 입력 데이터 세트인 Open Entity로 LUKE 평가하기](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_open_entity.ipynb) | Open Entity 데이터 세트로 *LukeForEntityClassification*을 평가하는 방법 | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_open_entity.ipynb) |
+| [관계 추출 데이터 세트인 TACRED로 LUKE 평가하기](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_tacred.ipynb) | TACRED 데이터 세트로 *LukeForEntityPairClassification*을 평가하는 방법 | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_tacred.ipynb) |
+| [중요 NER 벤치마크인 CoNLL-2003으로 LUKE 평가하기](https://github.com/studio-ousia/luke/blob/master/notebooks/huggingface_conll_2003.ipynb) | CoNLL-2003 데이터 세트로 *LukeForEntitySpanClassification*를 평가하는 방법 | [Ikuya Yamada](https://github.com/ikuyamada) |[](https://colab.research.google.com/github/studio-ousia/luke/blob/master/notebooks/huggingface_conll_2003.ipynb) |
+| [PubMed 데이터 세트로 BigBird-Pegasus 평가하기](https://github.com/vasudevgupta7/bigbird/blob/main/notebooks/bigbird_pegasus_evaluation.ipynb) | PubMed 데이터 세트로 *BigBirdPegasusForConditionalGeneration*를 평가하는 방법 | [Vasudev Gupta](https://github.com/vasudevgupta7) | [](https://colab.research.google.com/github/vasudevgupta7/bigbird/blob/main/notebooks/bigbird_pegasus_evaluation.ipynb) |
+| [Wav2Vec2를 사용해서 음성 감정 분류하기](https://github/m3hrdadfi/soxan/blob/main/notebooks/Emotion_recognition_in_Greek_speech_using_Wav2Vec2.ipynb) | 감정 분류를 위해 사전훈련된 Wav2Vec2 모델을 MEGA 데이터 세트에 활용하는 방법 | [Mehrdad Farahani](https://github.com/m3hrdadfi) | [](https://colab.research.google.com/github/m3hrdadfi/soxan/blob/main/notebooks/Emotion_recognition_in_Greek_speech_using_Wav2Vec2.ipynb) |
+| [DETR로 이미지에서 객체 탐지하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/DETR/DETR_minimal_example_(with_DetrFeatureExtractor).ipynb) | 훈련된 *DetrForObjectDetection* 모델을 사용하여 이미지에서 객체를 탐지하고 어텐션을 시각화하는 방법 | [Niels Rogge](https://github.com/NielsRogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/DETR/DETR_minimal_example_(with_DetrFeatureExtractor).ipynb) |
+| [사용자 지정 객체 탐지 데이터 세트로 DETR 미세 조정하기](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/DETR/Fine_tuning_DetrForObjectDetection_on_custom_dataset_(balloon).ipynb) | 사용자 지정 객체 탐지 데이터 세트로 *DetrForObjectDetection*을 미세 조정하는 방법 | [Niels Rogge](https://github.com/NielsRogge) | [](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/DETR/Fine_tuning_DetrForObjectDetection_on_custom_dataset_(balloon).ipynb) |
+| [개체명 인식을 위해 T5 미세 조정하기](https://github.com/ToluClassics/Notebooks/blob/main/T5_Ner_Finetuning.ipynb) | 개체명 인식 작업을 위해 *T5*를 미세 조정하는 방법 | [Ogundepo Odunayo](https://github.com/ToluClassics) | [](https://colab.research.google.com/drive/1obr78FY_cBmWY5ODViCmzdY6O1KB65Vc?usp=sharing) |
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/contributing.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/contributing.md
new file mode 100644
index 0000000000000000000000000000000000000000..f1c0a84ef32d848467026a812eaf776c2222a7fe
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/contributing.md
@@ -0,0 +1,330 @@
+
+
+# 🤗 Transformers에 기여하기 [[contribute-to-transformers]]
+
+누구나 🤗 Transformers에 기여할 수 있으며, 우리는 모든 사람의 기여를 소중히 생각합니다. 코드 기여는 커뮤니티를 돕는 유일한 방법이 아닙니다. 질문에 답하거나 다른 사람을 도와 문서를 개선하는 것도 매우 가치가 있습니다.
+
+🤗 Transformers를 널리 알리는 것도 큰 도움이 됩니다! 멋진 프로젝트들을 가능하게 한 🤗 Transformers 라이브러리에 대해 블로그 게시글에 언급하거나, 도움이 되었을 때마다 Twitter에 알리거나, 저장소에 ⭐️ 를 표시하여 감사 인사를 전해주세요.
+
+어떤 방식으로 기여하든 [행동 규칙](https://github.com/huggingface/transformers/blob/main/CODE_OF_CONDUCT.md)을 숙지하고 존중해주세요.
+
+**이 안내서는 멋진 [scikit-learn 기여 안내서](https://github.com/scikit-learn/scikit-learn/blob/main/CONTRIBUTING.md)에서 큰 영감을 받았습니다.**
+
+## 기여하는 방법 [[ways-to-contribute]]
+
+여러 가지 방법으로 🤗 Transformers에 기여할 수 있습니다:
+
+* 기존 코드의 미해결된 문제를 수정합니다.
+* 버그 또는 새로 추가되길 원하는 기능과 관련된 이슈를 제출합니다.
+* 새로운 모델을 구현합니다.
+* 예제나 문서에 기여합니다.
+
+어디서부터 시작할지 모르겠다면, [Good First Issue](https://github.com/huggingface/transformers/contribute) 목록을 확인해보세요. 이 목록은 초보자도 참여하기 쉬운 오픈 이슈 목록을 제공하며, 당신이 오픈소스에 처음으로 기여하는 데 큰 도움이 될 것입니다. 그저 작업하고 싶은 이슈에 댓글만 달아주면 됩니다.
+
+조금 더 도전적인 작업을 원한다면, [Good Second Issue](https://github.com/huggingface/transformers/labels/Good%20Second%20Issue) 목록도 확인해보세요. 이미 당신이 잘 하고 있다고 생각되더라도, 한 번 시도해보세요! 우리도 여러분을 도울 것입니다. 🚀
+
+> 커뮤니티에 이루어지는 모든 기여는 똑같이 소중합니다. 🥰
+
+## 미해결된 문제 수정하기 [[fixing-outstanding-issues]]
+
+기존 코드에서 발견한 문제점에 대한 해결책이 떠오른 경우, 언제든지 [기여를 시작](https://github.com/huggingface/transformers/blob/main/CONTRIBUTING.md/#create-a-pull-request)하고 Pull Request를 생성해주세요!
+
+## 버그 관련 이슈를 제기하거나 새로운 기능 요청하기 [[submitting-a-bugrelated-issue-or-feature-request]]
+
+버그 관련 이슈를 제기하거나 새로운 기능을 요청할 때는 다음 가이드라인을 최대한 준수해주세요. 이렇게 하면 좋은 피드백과 함께 빠르게 답변해 드릴 수 있습니다.
+
+### 버그를 발견하셨나요? [[did-you-find-a-bug]]
+
+🤗 Transformers 라이브러리는 사용 중에 겪는 문제를 보고해주는 사용자들 덕분에 더욱 견고해지고 신뢰할 수 있게 되었습니다.
+
+이슈를 보고하기 전에, 버그가 이미 **보고되지 않았는지** 확인해주세요. (GitHub의 이슈 탭 아래의 검색 바를 사용하세요). 이슈는 라이브러리 자체에서 발생한 버그어야 하며, 코드의 다른 부분과 관련된 것이 아니어야 합니다. 버그가 라이브러리의 문제로 발생하였는지 확실하지 않은 경우 먼저 [포럼](https://discuss.huggingface.co/)에서 질문해 주세요. 이렇게 하면 일반적인 질문보다 라이브러리와 관련된 문제를 더 빠르게 해결할 수 있습니다.
+
+버그가 이미 보고되지 않았다는 것을 확인했다면, 다음 정보를 포함하여 이슈를 제출해 주세요. 그러면 우리가 빠르게 해결할 수 있습니다:
+
+* 사용 중인 **운영체제 종류와 버전**, 그리고 **Python**, **PyTorch** 또는 **TensorFlow** 버전.
+* 버그를 30초 이내로 재현할 수 있는 간단하고 독립적인 코드 스니펫.
+* 예외가 발생한 경우 *전체* 트레이스백.
+* 스크린샷과 같이 도움이 될 것으로 생각되는 추가 정보를 첨부해 주세요.
+
+운영체제와 소프트웨어 버전을 자동으로 가져오려면 다음 명령을 실행하세요:
+
+```bash
+transformers-cli env
+```
+
+저장소의 루트 디렉터리에서도 같은 명령을 실행할 수 있습니다:
+
+```bash
+python src/transformers/commands/transformers_cli.py env
+```
+
+
+### 새로운 기능을 원하시나요? [[do-you-want-a-new-feature]]
+
+🤗 Transformers에서 사용하고 싶은 새로운 기능이 있다면, 다음 내용을 포함하여 이슈를 제출해 주세요:
+
+1. 이 기능이 필요한 *이유*는 무엇인가요? 라이브러리에 대한 문제나 불만과 관련이 있나요? 프로젝트에 필요한 기능인가요? 커뮤니티에 도움이 될 만한 기능인가요?
+
+ 어떤 내용이든 여러분의 이야기를 듣고 싶습니다!
+
+2. 요청하는 기능을 최대한 자세히 설명해 주세요. 더 많은 정보를 제공할수록 더 나은 도움을 드릴 수 있습니다.
+3. 해당 기능의 사용법을 보여주는 *코드 스니펫*을 제공해 주세요.
+4. 기능과 관련된 논문이 있는 경우 링크를 포함해 주세요.
+
+이슈가 잘 작성되었다면 이슈가 생성된 순간, 이미 80% 정도의 작업이 완료된 것입니다.
+
+이슈를 제기하는 데 도움이 될 만한 [템플릿](https://github.com/huggingface/transformers/tree/main/templates)도 준비되어 있습니다.
+
+## 새로운 모델을 구현하고 싶으신가요? [[do-you-want-to-implement-a-new-model]]
+
+새로운 모델은 계속해서 출시됩니다. 만약 여러분이 새로운 모델을 구현하고 싶다면 다음 정보를 제공해 주세요:
+
+* 모델에 대한 간단한 설명과 논문 링크.
+* 구현이 공개되어 있다면 구현 링크.
+* 모델 가중치가 사용 가능하다면 가중치 링크.
+
+만약 모델을 직접 기여하고 싶으시다면, 알려주세요. 🤗 Transformers에 추가할 수 있도록 도와드리겠습니다!
+
+[🤗 Transformers에 새로운 모델을 추가하는 방법](https://huggingface.co/docs/transformers/add_new_model)에 대한 기술적인 안내서도 있습니다.
+
+## 문서를 추가하고 싶으신가요? [[do-you-want-to-add-documentation]]
+
+우리는 언제나 더 명확하고 정확한 문서를 제공하기 위하여 개선점을 찾고 있습니다. 오탈자나 부족한 내용, 분명하지 않거나 부정확한 내용 등을 알려주시면 개선하는 데 도움이 됩니다. 관심이 있으시다면 변경하거나 기여하실 수 있도록 도와드리겠습니다!
+
+문서를 생성, 빌드 및 작성하는 방법에 대한 자세한 내용은 [README](https://github.com/huggingface/transformers/tree/main/docs) 문서를 확인해 주세요.
+
+## 풀 리퀘스트(Pull Request) 생성하기 [[create-a-pull-request]]
+
+코드를 작성하기 전에 기존의 Pull Request나 이슈를 검색하여 누군가 이미 동일한 작업을 하고 있는지 확인하는 것이 좋습니다. 확실하지 않다면 피드백을 받기 위해 이슈를 열어보는 것이 좋습니다.
+
+🤗 Transformers에 기여하기 위해서는 기본적인 `git` 사용 능력이 필요합니다. `git`은 사용하기 쉬운 도구는 아니지만, 매우 훌륭한 매뉴얼을 제공합니다. 쉘(shell)에서 `git --help`을 입력하여 확인해보세요! 만약 책을 선호한다면, [Pro Git](https://git-scm.com/book/en/v2)은 매우 좋은 참고 자료가 될 것입니다.
+
+🤗 Transformers에 기여하려면 **[Python 3.9](https://github.com/huggingface/transformers/blob/main/setup.py#L426)** 이상의 버전이 필요합니다. 기여를 시작하려면 다음 단계를 따르세요:
+
+1. 저장소 페이지에서 **[Fork](https://github.com/huggingface/transformers/fork)** 버튼을 클릭하여 저장소를 포크하세요. 이렇게 하면 코드의 복사본이 여러분의 GitHub 사용자 계정 아래에 생성됩니다.
+
+2. 포크한 저장소를 로컬 디스크로 클론하고, 기본 저장소를 원격(remote)으로 추가하세요:
+
+ ```bash
+ git clone git@github.com:/transformers.git
+ cd transformers
+ git remote add upstream https://github.com/huggingface/transformers.git
+ ```
+
+3. 개발 변경 사항을 저장할 새 브랜치를 생성하세요:
+
+ ```bash
+ git checkout -b a-descriptive-name-for-my-changes
+ ```
+
+ 🚨 절대 `main` 브랜치에서 작업하지 **마세요!**
+
+4. 가상 환경에서 다음 명령을 실행하여 개발 환경을 설정하세요:
+
+ ```bash
+ pip install -e ".[dev]"
+ ```
+
+ 만약 이미 가상 환경에 🤗 Transformers가 설치되어 있다면, `-e` 플래그를 사용하여 설치하기 전에 `pip uninstall transformers`로 제거해주세요.
+
+ 여러분의 운영체제에 따라서, 그리고 🤗 Transformers의 선택적 의존성의 수가 증가하면서, 이 명령이 실패할 수도 있습니다. 그럴 경우 사용하려는 딥러닝 프레임워크(PyTorch, TensorFlow, 그리고/또는 Flax)를 설치한 후 아래 명령을 실행해주세요:
+
+ ```bash
+ pip install -e ".[quality]"
+ ```
+
+ 대부분의 경우 이것으로 충분할 것입니다.
+
+5. 브랜치에서 기능을 개발하세요.
+
+ 코드를 작업하는 동안 테스트 스위트(test suite)가 통과하는지 확인하세요. 다음과 같이 변경 사항에 영향을 받는 테스트를 실행하세요:
+
+ ```bash
+ pytest tests/.py
+ ```
+
+ 테스트에 대한 더 많은 정보는 [테스트](https://huggingface.co/docs/transformers/testing) 가이드를 확인하세요.
+
+ 🤗 Transformers는 `black`과 `ruff`를 사용하여 소스 코드의 형식을 일관되게 유지합니다. 변경 사항을 적용한 후에는 다음 명령으로 자동으로 스타일 교정 및 코드 검증을 수행하세요:
+
+ ```bash
+ make fixup
+ ```
+
+ 이것은 또한 작업 중인 PR에서 수정한 파일에서만 작동하도록 최적화되어 있습니다.
+
+ 검사를 하나씩 실행하려는 경우, 다음 명령으로 스타일 교정을 적용할 수 있습니다:
+
+ ```bash
+ make style
+ ```
+
+ 🤗 Transformers는 또한 `ruff`와 몇 가지 사용자 정의 스크립트를 사용하여 코딩 실수를 확인합니다. CI를 통해 품질 관리가 수행되지만, 다음 명령으로 동일한 검사를 실행할 수 있습니다:
+
+ ```bash
+ make quality
+ ```
+
+ 마지막으로, 새 모델을 추가할 때 일부 파일을 업데이트하는 것을 잊지 않도록 하기 위한 많은 스크립트가 있습니다. 다음 명령으로 이러한 스크립트를 실행할 수 있습니다:
+
+ ```bash
+ make repo-consistency
+ ```
+
+ 이러한 검사에 대해 자세히 알아보고 관련 문제를 해결하는 방법은 [Pull Request에 대한 검사](https://huggingface.co/docs/transformers/pr_checks) 가이드를 확인하세요.
+
+ 만약 `docs/source` 디렉터리 아래의 문서를 수정하는 경우, 문서가 빌드될 수 있는지 확인하세요. 이 검사는 Pull Request를 열 때도 CI에서 실행됩니다. 로컬 검사를 실행하려면 문서 빌더를 설치해야 합니다:
+
+ ```bash
+ pip install ".[docs]"
+ ```
+
+ 저장소의 루트 디렉터리에서 다음 명령을 실행하세요:
+
+ ```bash
+ doc-builder build transformers docs/source/en --build_dir ~/tmp/test-build
+ ```
+
+ 이 명령은 `~/tmp/test-build` 폴더에 문서를 빌드하며, 생성된 Markdown 파일을 선호하는 편집기로 확인할 수 있습니다. Pull Request를 열 때 GitHub에서 문서를 미리 볼 수도 있습니다.
+
+ 변경 사항에 만족하면 `git add`로 변경된 파일을 추가하고, `git commit`으로 변경 사항을 로컬에 기록하세요:
+
+ ```bash
+ git add modified_file.py
+ git commit
+ ```
+
+ [좋은 커밋 메시지](https://chris.beams.io/posts/git-commit/)를 작성하여 변경 사항을 명확하게 전달하세요!
+
+ 변경 사항을 프로젝트 원본 저장소와 동기화하려면, PR을 *열기 전에* 브랜치를 `upstream/branch`로 리베이스(rebase)하세요. 또는 관리자의 요청에 이 작업이 필요할 수 있습니다:
+
+ ```bash
+ git fetch upstream
+ git rebase upstream/main
+ ```
+
+ 변경 사항을 브랜치에 푸시하세요:
+
+ ```bash
+ git push -u origin a-descriptive-name-for-my-changes
+ ```
+
+ 이미 PR을 열었다면, `--force` 플래그와 함께 강제 푸시해야 합니다. 아직 PR이 열리지 않았다면 정상적으로 변경 사항을 푸시하면 됩니다.
+
+6. 이제 GitHub에서 포크한 저장소로 이동하고 **Pull request(풀 리퀘스트)**를 클릭하여 Pull Request를 열 수 있습니다. 아래의 [체크리스트](https://github.com/huggingface/transformers/blob/main/CONTRIBUTING.md/#pull-request-checklist)에서 모든 항목에 체크 표시를 하세요. 준비가 완료되면 프로젝트 관리자에게 변경 사항을 보내 검토를 요청할 수 있습니다.
+
+7. 관리자가 변경 사항을 요청해도 괜찮습니다. 핵심 기여자들도 동일한 상황을 겪습니다! 모두가 변경 사항을 Pull Request에서 볼 수 있도록, 로컬 브랜치에서 작업하고 변경 사항을 포크한 저장소로 푸시하세요. 그러면 변경 사항이 자동으로 Pull Request에 나타납니다.
+
+### Pull Request 체크리스트 [[pull-request-checklist]]
+
+☐ Pull Request 제목은 기여 내용을 요약해야 합니다.
+☐ Pull Request가 이슈를 해결하는 경우, Pull Request 설명에 이슈 번호를 언급하여 연관되어 있음을 알려주세요. (이슈를 확인하는 사람들이 해당 이슈에 대한 작업이 진행 중임을 알 수 있게 합니다).
+☐ 작업이 진행중이라면 제목 앞에 `[WIP]`를 붙여주세요. 중복 작업을 피하고 병합할 준비가 된 PR과 구분하기에 유용합니다.
+☐ 기존 테스트를 통과하는지 확인하세요.
+☐ 새로운 기능을 추가하는 경우, 해당 기능에 대한 테스트도 추가하세요.
+ - 새 모델을 추가하는 경우, `ModelTester.all_model_classes = (MyModel, MyModelWithLMHead,...)`을 사용하여 일반적인 테스트를 활성화하세요.
+ - 새 `@slow` 테스트를 추가하는 경우, 다음 명령으로 테스트를 통과하는지 확인하세요: `RUN_SLOW=1 python -m pytest tests/models/my_new_model/test_my_new_model.py`.
+ - 새 토크나이저를 추가하는 경우, 테스트를 작성하고 다음 명령으로 테스트를 통과하는지 확인하세요: `RUN_SLOW=1 python -m pytest tests/models/{your_model_name}/test_tokenization_{your_model_name}.py`.
+ - CircleCI에서는 느린 테스트를 실행하지 않지만, GitHub Actions에서는 매일 밤 실행됩니다!
+
+☐ 모든 공개 메소드는 유용한 기술문서를 가져야 합니다 (예를 들어 [`modeling_bert.py`](https://github.com/huggingface/transformers/blob/main/src/transformers/models/bert/modeling_bert.py) 참조).
+☐ 저장소가 빠르게 성장하고 있으므로 저장소에 상당한 부담을 주는 이미지, 동영상 및 기타 텍스트가 아닌 파일은 추가하지 마세요. 대신 [`hf-internal-testing`](https://huggingface.co/hf-internal-testing)과 같은 Hub 저장소를 사용하여 이러한 파일을 호스팅하고 URL로 참조하세요. 문서와 관련된 이미지는 다음 저장소에 배치하는 것을 권장합니다: [huggingface/documentation-images](https://huggingface.co/datasets/huggingface/documentation-images). 이 데이터셋 저장소에서 PR을 열어서 Hugging Face 멤버에게 병합을 요청할 수 있습니다.
+
+Pull Request에서 실행되는 검사에 대한 자세한 정보는 [Pull Request에 대한 검사](https://huggingface.co/docs/transformers/pr_checks) 가이드를 확인하세요.
+
+### 테스트 [[tests]]
+
+라이브러리 동작과 여러 예제를 테스트할 수 있는 광범위한 테스트 스위트가 포함되어 있습니다. 라이브러리 테스트는 [tests](https://github.com/huggingface/transformers/tree/main/tests) 폴더에, 예제 테스트는 [examples](https://github.com/huggingface/transformers/tree/main/examples) 폴더에 있습니다.
+
+속도가 빠른 `pytest`와 `pytest-xdist`를 선호합니다. 저장소의 루트 디렉터리에서 테스트를 실행할 *하위 폴더 경로 또는 테스트 파일 경로*를 지정하세요:
+
+```bash
+python -m pytest -n auto --dist=loadfile -s -v ./tests/models/my_new_model
+```
+
+마찬가지로 `examples` 디렉터리에서도 *하위 폴더 경로 또는 테스트 파일 경로*를 지정하세요. 예를 들어, 다음 명령은 PyTorch `examples` 디렉터리의 텍스트 분류 하위 폴더를 테스트합니다:
+
+```bash
+pip install -r examples/xxx/requirements.txt # only needed the first time
+python -m pytest -n auto --dist=loadfile -s -v ./examples/pytorch/text-classification
+```
+
+이것이 실제로 `make test` 및 `make test-examples` 명령이 구현되는 방식입니다 (`pip install`은 제외합니다)!
+
+또한 특정 기능만 테스트하기 위한 더 작은 테스트를 지정할 수 있습니다.
+
+기본적으로 느린 테스트는 건너뛰지만 `RUN_SLOW` 환경 변수를 `yes`로 설정하여 실행할 수 있습니다. 이렇게 하면 많은 기가바이트 단위의 모델이 다운로드되므로 충분한 디스크 공간, 좋은 인터넷 연결과 많은 인내가 필요합니다!
+
+
+
+테스트를 실행하려면 *하위 폴더 경로 또는 테스트 파일 경로*를 지정하세요. 그렇지 않으면 `tests` 또는 `examples` 폴더의 모든 테스트를 실행하게 되어 매우 긴 시간이 걸립니다!
+
+
+
+```bash
+RUN_SLOW=yes python -m pytest -n auto --dist=loadfile -s -v ./tests/models/my_new_model
+RUN_SLOW=yes python -m pytest -n auto --dist=loadfile -s -v ./examples/pytorch/text-classification
+```
+
+느린 테스트와 마찬가지로, 다음과 같이 테스트 중에 기본적으로 활성화되지 않는 다른 환경 변수도 있습니다:
+- `RUN_CUSTOM_TOKENIZERS`: 사용자 정의 토크나이저 테스트를 활성화합니다.
+
+더 많은 환경 변수와 추가 정보는 [testing_utils.py](src/transformers/testing_utils.py)에서 찾을 수 있습니다.
+
+🤗 Transformers는 테스트 실행기로 `pytest`를 사용합니다. 그러나 테스트 스위트 자체에서는 `pytest` 관련 기능을 사용하지 않습니다.
+
+이것은 `unittest`가 완전히 지원된다는 것을 의미합니다. 다음은 `unittest`로 테스트를 실행하는 방법입니다:
+
+```bash
+python -m unittest discover -s tests -t . -v
+python -m unittest discover -s examples -t examples -v
+```
+
+### 스타일 가이드 [[style-guide]]
+
+문서는 [Google Python 스타일 가이드](https://google.github.io/styleguide/pyguide.html)를 따릅니다. 자세한 정보는 [문서 작성 가이드](https://github.com/huggingface/transformers/tree/main/docs#writing-documentation---specification)를 확인하세요.
+
+### Windows에서 개발 [[develop-on-windows]]
+
+Windows에서 개발할 경우([Windows Subsystem for Linux](https://learn.microsoft.com/en-us/windows/wsl/) 또는 WSL에서 작업하지 않는 한) Windows `CRLF` 줄 바꿈을 Linux `LF` 줄 바꿈으로 변환하도록 git을 구성해야 합니다:
+
+```bash
+git config core.autocrlf input
+```
+
+Windows에서 `make` 명령을 실행하는 한 가지 방법은 MSYS2를 사용하는 것입니다:
+
+1. [MSYS2](https://www.msys2.org/)를 다운로드합니다. `C:\msys64`에 설치되었다고 가정합니다.
+2. CLI에서 `C:\msys64\msys2.exe`를 엽니다 (시작 메뉴에서 사용 가능해야 함).
+3. 쉘에서 다음을 실행하여: `pacman -Syu` 및 `pacman -S make`로 `make`를 설치합니다.
+4. 환경 변수 PATH에 `C:\msys64\usr\bin`을 추가하세요.
+
+이제 모든 터미널 (PowerShell, cmd.exe 등)에서 `make`를 사용할 수 있습니다! 🎉
+
+### 포크한 저장소를 상위 원본 브랜치(main)과 동기화하기 (Hugging Face 저장소) [[sync-a-forked-repository-with-upstream-main-the-hugging-face-repository]]
+
+포크한 저장소의 main 브랜치를 업데이트할 때, 다음 단계를 따라 수행해주세요. 이렇게 하면 각 upstream PR에 참조 노트가 추가되는 것을 피하고 이러한 PR에 관여하는 개발자들에게 불필요한 알림이 전송되는 것을 방지할 수 있습니다.
+
+1. 가능하면 포크된 저장소의 브랜치 및 PR을 사용하여 upstream과 동기화하지 마세요. 대신 포크된 main 저장소에 직접 병합하세요.
+2. PR이 반드시 필요한 경우, 브랜치를 확인한 후 다음 단계를 사용하세요:
+
+ ```bash
+ git checkout -b your-branch-for-syncing
+ git pull --squash --no-commit upstream main
+ git commit -m ''
+ git push --set-upstream origin your-branch-for-syncing
+ ```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/conversations.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/conversations.md
new file mode 100644
index 0000000000000000000000000000000000000000..920cb1387860865e6f01ff47b79c50a2e9c4bea3
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/conversations.md
@@ -0,0 +1,306 @@
+
+
+# Transformers로 채팅하기[[chatting-with-transformers]]
+
+이 글을 보고 있다면 **채팅 모델**에 대해 어느 정도 알고 계실 것입니다.
+채팅 모델이란 메세지를 주고받을 수 있는 대화형 인공지능입니다.
+대표적으로 ChatGPT가 있고, 이와 비슷하거나 더 뛰어난 오픈소스 채팅 모델이 많이 존재합니다.
+이러한 모델들은 무료 다운로드할 수 있으며, 로컬에서 실행할 수 있습니다.
+크고 무거운 모델은 고성능 하드웨어와 메모리가 필요하지만,
+저사양 GPU 혹은 일반 데스크탑이나 노트북 CPU에서도 잘 작동하는 소형 모델들도 있습니다.
+
+이 가이드는 채팅 모델을 처음 사용하는 분들에게 유용할 것입니다.
+우리는 간편한 고수준(High-Level) "pipeline"을 통해 빠른 시작 가이드를 진행할 것입니다.
+가이드에는 채팅 모델을 바로 시작할 때 필요한 모든 정보가 담겨 있습니다.
+빠른 시작 가이드 이후에는 채팅 모델이 정확히 무엇인지, 적절한 모델을 선택하는 방법과,
+채팅 모델을 사용하는 각 단계의 저수준(Low-Level) 분석 등 더 자세한 정보를 다룰 것입니다.
+또한 채팅 모델의 성능과 메모리 사용을 최적화하는 방법에 대한 팁도 제공할 것입니다.
+
+
+## 빠른 시작[[quickstart]]
+
+자세히 볼 여유가 없는 분들을 위해 간단히 요약해 보겠습니다:
+채팅 모델은 대화 메세지를 계속해서 생성해 나갑니다.
+즉, 짤막한 채팅 메세지를 모델에게 전달하면, 모델은 이를 바탕으로 응답을 추가하며 대화를 이어 나갑니다.
+이제 실제로 어떻게 작동하는지 살펴보겠습니다.
+먼저, 채팅을 만들어 보겠습니다:
+
+
+```python
+chat = [
+ {"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."},
+ {"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"}
+]
+```
+
+주목하세요, 대화를 처음 시작할 때 유저 메세지 이외의도, 별도의 **시스템** 메세지가 필요할 수 있습니다.
+모든 채팅 모델이 시스템 메세지를 지원하는 것은 아니지만,
+지원하는 경우에는 시스템 메세지는 대화에서 모델이 어떻게 행동해야 하는지를 지시할 수 있습니다.
+예를 들어, 유쾌하거나 진지하고자 할 때, 짧은 답변이나 긴 답변을 원할 때 등을 설정할 수 있습니다.
+시스템 메세지를 생략하고
+"You are a helpful and intelligent AI assistant who responds to user queries."
+와 같은 간단한 프롬프트를 사용하는 것도 가능합니다.
+
+채팅을 시작했다면 대화를 이어 나가는 가장 빠른 방법은 [`TextGenerationPipeline`]를 사용하는 것입니다.
+한번 `LLaMA-3`를 사용하여 이를 시연해 보겠습니다.
+우선 `LLaMA-3`를 사용하기 위해서는 승인이 필요합니다. [권한 신청](https://huggingface.co/meta-llama/Meta-Llama-3-8B-Instruct)을 하고 Hugging Face 계정으로 로그인한 후에 사용할 수 있습니다.
+또한 우리는 `device_map="auto"`를 사용합니다. GPU 메모리가 충분하다면 로드될 것입니다.
+그리고 메모리 절약을 위해 dtype을 `torch.bfloat16`으로 설정할 것입니다.
+
+```python
+import torch
+from transformers import pipeline
+
+pipe = pipeline("text-generation", "meta-llama/Meta-Llama-3-8B-Instruct", torch_dtype=torch.bfloat16, device_map="auto")
+response = pipe(chat, max_new_tokens=512)
+print(response[0]['generated_text'][-1]['content'])
+```
+
+이후 실행을 하면 아래와 같이 출력됩니다:
+
+```text
+(sigh) Oh boy, you're asking me for advice? You're gonna need a map, pal! Alright,
+alright, I'll give you the lowdown. But don't say I didn't warn you, I'm a robot, not a tour guide!
+
+So, you wanna know what's fun to do in the Big Apple? Well, let me tell you, there's a million
+things to do, but I'll give you the highlights. First off, you gotta see the sights: the Statue of
+Liberty, Central Park, Times Square... you know, the usual tourist traps. But if you're lookin' for
+something a little more... unusual, I'd recommend checkin' out the Museum of Modern Art. It's got
+some wild stuff, like that Warhol guy's soup cans and all that jazz.
+
+And if you're feelin' adventurous, take a walk across the Brooklyn Bridge. Just watch out for
+those pesky pigeons, they're like little feathered thieves! (laughs) Get it? Thieves? Ah, never mind.
+
+Now, if you're lookin' for some serious fun, hit up the comedy clubs in Greenwich Village. You might
+even catch a glimpse of some up-and-coming comedians... or a bunch of wannabes tryin' to make it big. (winks)
+
+And finally, if you're feelin' like a real New Yorker, grab a slice of pizza from one of the many amazing
+pizzerias around the city. Just don't try to order a "robot-sized" slice, trust me, it won't end well. (laughs)
+
+So, there you have it, pal! That's my expert advice on what to do in New York. Now, if you'll
+excuse me, I've got some oil changes to attend to. (winks)
+```
+
+채팅을 계속하려면, 자신의 답장을 추가하면 됩니다.
+파이프라인에서 반환된 `response` 객체에는 현재까지 모든 채팅을 포함하고 있으므로
+메세지를 추가하고 다시 전달하기만 하면 됩니다.
+
+```python
+chat = response[0]['generated_text']
+chat.append(
+ {"role": "user", "content": "Wait, what's so wild about soup cans?"}
+)
+response = pipe(chat, max_new_tokens=512)
+print(response[0]['generated_text'][-1]['content'])
+```
+
+이후 실행을 하면 아래와 같이 출력됩니다:
+
+```text
+(laughs) Oh, you're killin' me, pal! You don't get it, do you? Warhol's soup cans are like, art, man!
+It's like, he took something totally mundane, like a can of soup, and turned it into a masterpiece. It's
+like, "Hey, look at me, I'm a can of soup, but I'm also a work of art!"
+(sarcastically) Oh, yeah, real original, Andy.
+
+But, you know, back in the '60s, it was like, a big deal. People were all about challenging the
+status quo, and Warhol was like, the king of that. He took the ordinary and made it extraordinary.
+And, let me tell you, it was like, a real game-changer. I mean, who would've thought that a can of soup could be art? (laughs)
+
+But, hey, you're not alone, pal. I mean, I'm a robot, and even I don't get it. (winks)
+But, hey, that's what makes art, art, right? (laughs)
+```
+
+이 튜토리얼의 후반부에서는 성능과 메모리 관리,
+그리고 사용자의 필요에 맞는 채팅 모델 선택과 같은 구체적인 주제들을 다룰 것입니다.
+
+## 채팅 모델 고르기[[choosing-a-chat-model]]
+
+[Hugging Face Hub](https://huggingface.co/models?pipeline_tag=text-generation&sort=trending)는 채팅 모델을 다양하게 제공하고 있습니다.
+처음 사용하는 사람에게는 모델을 선택하기가 어려울지 모릅니다.
+하지만 걱정하지 마세요! 두 가지만 명심하면 됩니다:
+
+- 모델의 크기는 실행 속도와 메모리에 올라올 수 있는지 여부를 결정.
+- 모델이 생성한 출력의 품질.
+
+일반적으로 이러한 요소들은 상관관계가 있습니다. 더 큰 모델일수록 더 뛰어난 성능을 보이는 경향이 있지만, 동일한 크기의 모델이라도 유의미한 차이가 날 수 있습니다!
+
+### 모델의 명칭과 크기[[size-and-model-naming]]
+
+모델의 크기는 모델 이름에 있는 숫자로 쉽게 알 수 있습니다.
+예를 들어, "8B" 또는 "70B"와 같은 숫자는 모델의 **파라미터** 수를 나타냅니다.
+양자화된 경우가 아니라면, 파라미터 하나당 약 2바이트의 메모리가 필요하다고 예상 가능합니다.
+따라서 80억 개의 파라미터를 가진 "8B" 모델은 16GB의 메모리를 차지하며, 추가적인 오버헤드를 위한 약간의 여유가 필요합니다.
+이는 3090이나 4090와 같은 24GB의 메모리를 갖춘 하이엔드 GPU에 적합합니다.
+
+일부 채팅 모델은 "Mixture of Experts" 모델입니다.
+이러한 모델은 크기를 "8x7B" 또는 "141B-A35B"와 같이 다르게 표시하곤 합니다.
+숫자가 다소 모호하다 느껴질 수 있지만, 첫 번째 경우에는 약 56억(8x7) 개의 파라미터가 있고,
+두 번째 경우에는 약 141억 개의 파라미터가 있다고 해석할 수 있습니다.
+
+양자화는 파라미터당 메모리 사용량을 8비트, 4비트, 또는 그 이하로 줄이는 데 사용됩니다.
+이 주제에 대해서는 아래의 [메모리 고려사항](#memory-considerations) 챕터에서 더 자세히 다룰 예정입니다.
+
+### 그렇다면 어떤 채팅 모델이 가장 좋을까요?[[but-which-chat-model-is-best]]
+모델의 크기 외에도 고려할 점이 많습니다.
+이를 한눈에 살펴보려면 **리더보드**를 참고하는 것이 좋습니다.
+가장 인기 있는 리더보드 두 가지는 [OpenLLM Leaderboard](https://huggingface.co/spaces/HuggingFaceH4/open_llm_leaderboard)와 [LMSys Chatbot Arena Leaderboard](https://chat.lmsys.org/?leaderboard)입니다.
+LMSys 리더보드에는 독점 모델도 포함되어 있으니,
+`license` 열에서 접근 가능한 모델을 선택한 후
+[Hugging Face Hub](https://huggingface.co/models?pipeline_tag=text-generation&sort=trending)에서 검색해 보세요.
+
+### 전문 분야[[specialist-domains]]
+일부 모델은 의료 또는 법률 텍스트와 같은 특정 도메인이나 비영어권 언어에 특화되어 있기도 합니다.
+이러한 도메인에서 작업할 경우 특화된 모델이 좋은 성능을 보일 수 있습니다.
+하지만 항상 그럴 것이라 단정하기는 힘듭니다.
+특히 모델의 크기가 작거나 오래된 모델인 경우,
+최신 범용 모델이 더 뛰어날 수 있습니다.
+다행히도 [domain-specific leaderboards](https://huggingface.co/blog/leaderboard-medicalllm)가 점차 등장하고 있어, 특정 도메인에 최고의 모델을 쉽게 찾을 수 있을 것입니다.
+
+
+## 파이프라인 내부는 어떻게 되어있는가?[[what-happens-inside-the-pipeline]]
+위의 빠른 시작에서는 고수준(High-Level) 파이프라인을 사용하였습니다.
+이는 간편한 방법이지만, 유연성은 떨어집니다.
+이제 더 저수준(Low-Level) 접근 방식을 통해 대화에 포함된 각 단계를 살펴보겠습니다.
+코드 샘플로 시작한 후 이를 분석해 보겠습니다:
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+import torch
+
+# 입력값을 사전에 준비해 놓습니다
+chat = [
+ {"role": "system", "content": "You are a sassy, wise-cracking robot as imagined by Hollywood circa 1986."},
+ {"role": "user", "content": "Hey, can you tell me any fun things to do in New York?"}
+]
+
+# 1: 모델과 토크나이저를 불러옵니다
+model = AutoModelForCausalLM.from_pretrained("meta-llama/Meta-Llama-3-8B-Instruct", device_map="auto", torch_dtype=torch.bfloat16)
+tokenizer = AutoTokenizer.from_pretrained("meta-llama/Meta-Llama-3-8B-Instruct")
+
+# 2: 채팅 템플릿에 적용합니다
+formatted_chat = tokenizer.apply_chat_template(chat, tokenize=False, add_generation_prompt=True)
+print("Formatted chat:\n", formatted_chat)
+
+# 3: 채팅을 토큰화합니다 (바로 이전 과정에서 tokenized=True로 설정하면 한꺼번에 처리할 수 있습니다)
+inputs = tokenizer(formatted_chat, return_tensors="pt", add_special_tokens=False)
+# 토큰화된 입력값을 모델이 올라와 있는 기기(CPU/GPU)로 옮깁니다.
+inputs = {key: tensor.to(model.device) for key, tensor in inputs.items()}
+print("Tokenized inputs:\n", inputs)
+
+# 4: 모델로부터 응답을 생성합니다
+outputs = model.generate(**inputs, max_new_tokens=512, temperature=0.1)
+print("Generated tokens:\n", outputs)
+
+# 5: 모델이 출력한 토큰을 다시 문자열로 디코딩합니다
+decoded_output = tokenizer.decode(outputs[0][inputs['input_ids'].size(1):], skip_special_tokens=True)
+print("Decoded output:\n", decoded_output)
+```
+여기에는 각 부분이 자체 문서가 될 수 있을 만큼 많은 내용이 담겨 있습니다!
+너무 자세히 설명하기보다는 넓은 개념을 다루고, 세부 사항은 링크된 문서에서 다루겠습니다.
+주요 단계는 다음과 같습니다:
+
+1. [모델](https://huggingface.co/learn/nlp-course/en/chapter2/3)과 [토크나이저](https://huggingface.co/learn/nlp-course/en/chapter2/4?fw=pt)를 Hugging Face Hub에서 로드합니다.
+2. 대화는 토크나이저의 [채팅 템플릿](https://huggingface.co/docs/transformers/main/en/chat_templating)을 사용하여 양식을 구성합니다.
+3. 구성된 채팅은 토크나이저를 사용하여 [토큰화](https://huggingface.co/learn/nlp-course/en/chapter2/4)됩니다.
+4. 모델에서 응답을 [생성](https://huggingface.co/docs/transformers/en/llm_tutorial)합니다.
+5. 모델이 출력한 토큰을 다시 문자열로 디코딩합니다.
+
+## 성능, 메모리와 하드웨어[[performance-memory-and-hardware]]
+이제 대부분의 머신 러닝 작업이 GPU에서 실행된다는 것을 아실 겁니다.
+다소 느리기는 해도 CPU에서 채팅 모델이나 언어 모델로부터 텍스트를 생성하는 것도 가능합니다.
+하지만 모델을 GPU 메모리에 올려놓을 수만 있다면, GPU를 사용하는 것이 일반적으로 더 선호되는 방식입니다.
+
+### 메모리 고려사항[[memory-considerations]]
+
+기본적으로, [`TextGenerationPipeline`]이나 [`AutoModelForCausalLM`]과 같은
+Hugging Face 클래스는 모델을 `float32` 정밀도(Precision)로 로드합니다.
+이는 파라미터당 4바이트(32비트)를 필요로 하므로,
+80억 개의 파라미터를 가진 "8B" 모델은 약 32GB의 메모리를 필요로 한다는 것을 의미합니다.
+하지만 이는 낭비일 수 있습니다!
+대부분의 최신 언어 모델은 파라미터당 2바이트를 사용하는 "bfloat16" 정밀도(Precision)로 학습됩니다.
+하드웨어가 이를 지원하는 경우(Nvidia 30xx/Axxx 이상),
+`torch_dtype` 파라미터로 위와 같이 `bfloat16` 정밀도(Precision)로 모델을 로드할 수 있습니다.
+
+또한, 16비트보다 더 낮은 정밀도(Precision)로 모델을 압축하는
+"양자화(quantization)" 방법을 사용할 수도 있습니다.
+이 방법은 모델의 가중치를 손실 압축하여 각 파라미터를 8비트,
+4비트 또는 그 이하로 줄일 수 있습니다.
+특히 4비트에서 모델의 출력이 부정적인 영향을 받을 수 있지만,
+더 크고 강력한 채팅 모델을 메모리에 올리기 위해 이 같은 트레이드오프를 감수할 가치가 있습니다.
+이제 `bitsandbytes`를 사용하여 이를 실제로 확인해 보겠습니다:
+
+```python
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_8bit=True) # You can also try load_in_4bit
+model = AutoModelForCausalLM.from_pretrained("meta-llama/Meta-Llama-3-8B-Instruct", device_map="auto", quantization_config=quantization_config)
+```
+
+위의 작업은 `pipeline` API에도 적용 가능합니다:
+
+```python
+from transformers import pipeline, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_8bit=True) # You can also try load_in_4bit
+pipe = pipeline("text-generation", "meta-llama/Meta-Llama-3-8B-Instruct", device_map="auto", model_kwargs={"quantization_config": quantization_config})
+```
+
+`bitsandbytes` 외에도 모델을 양자화하는 다양한 방법이 있습니다.
+자세한 내용은 [Quantization guide](./quantization)를 참조해 주세요.
+
+
+### 성능 고려사항[[performance-considerations]]
+
+
+
+언어 모델 성능과 최적화에 대한 보다 자세한 가이드는 [LLM Inference Optimization](./llm_optims)을 참고하세요.
+
+
+
+
+일반적으로 더 큰 채팅 모델은 메모리를 더 많이 요구하고,
+속도도 느려지는 경향이 있습니다. 구체적으로 말하자면,
+채팅 모델에서 텍스트를 생성할 때는 컴퓨팅 파워보다 **메모리 대역폭**이 병목 현상을 일으키는 경우가 많습니다.
+이는 모델이 토큰을 하나씩 생성할 때마다 파라미터를 메모리에서 읽어야 하기 때문입니다.
+따라서 채팅 모델에서 초당 생성할 수 있는 토큰 수는 모델이 위치한 메모리의 대역폭을 모델의 크기로 나눈 값에 비례합니다.
+
+위의 예제에서는 모델이 bfloat16 정밀도(Precision)로 로드될 때 용량이 약 16GB였습니다.
+이 경우, 모델이 생성하는 각 토큰마다 16GB를 메모리에서 읽어야 한다는 의미입니다.
+총 메모리 대역폭은 소비자용 CPU에서는 20-100GB/sec,
+소비자용 GPU나 Intel Xeon, AMD Threadripper/Epyc,
+애플 실리콘과 같은 특수 CPU에서는 200-900GB/sec,
+데이터 센터 GPU인 Nvidia A100이나 H100에서는 최대 2-3TB/sec에 이를 수 있습니다.
+이러한 정보는 각자 하드웨어에서 생성 속도를 예상하는 데 도움이 될 것입니다.
+
+따라서 텍스트 생성 속도를 개선하려면 가장 간단한 방법은 모델의 크기를 줄이거나(주로 양자화를 사용),
+메모리 대역폭이 더 높은 하드웨어를 사용하는 것입니다.
+이 대역폭 병목 현상을 피할 수 있는 고급 기술도 여러 가지 있습니다.
+가장 일반적인 방법은 [보조 생성](https://huggingface.co/blog/assisted-generation), "추측 샘플링"이라고 불리는 기술입니다.
+이 기술은 종종 더 작은 "초안 모델"을 사용하여 여러 개의 미래 토큰을 한 번에 추측한 후,
+채팅 모델로 생성 결과를 확인합니다.
+만약 채팅 모델이 추측을 확인하면, 한 번의 순전파에서 여러 개의 토큰을 생성할 수 있어
+병목 현상이 크게 줄어들고 생성 속도가 빨라집니다.
+
+마지막으로, "Mixture of Experts" (MoE) 모델에 대해서도 짚고 넘어가 보도록 합니다.
+Mixtral, Qwen-MoE, DBRX와 같은 인기 있는 채팅 모델이 바로 MoE 모델입니다.
+이 모델들은 토큰을 생성할 때 모든 파라미터가 사용되지 않습니다.
+이로 인해 MoE 모델은 전체 크기가 상당히 클 수 있지만,
+차지하는 메모리 대역폭은 낮은 편입니다.
+따라서 동일한 크기의 일반 "조밀한(Dense)" 모델보다 몇 배 빠를 수 있습니다.
+하지만 보조 생성과 같은 기술은 MoE 모델에서 비효율적일 수 있습니다.
+새로운 추측된 토큰이 추가되면서 더 많은 파라미터가 활성화되기 때문에,
+MoE 아키텍처가 제공하는 속도 이점이 상쇄될 수 있습니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/create_a_model.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/create_a_model.md
new file mode 100644
index 0000000000000000000000000000000000000000..b911669bb174b96ac8b43c9c9490bc16b75f3a7e
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/create_a_model.md
@@ -0,0 +1,388 @@
+
+
+# 맞춤형 아키텍처 만들기[[create-a-custom-architecture]]
+
+[`AutoClass`](model_doc/auto)는 모델 아키텍처를 자동으로 추론하고 미리 학습된 configuration과 가중치를 다운로드합니다. 일반적으로 체크포인트에 구애받지 않는 코드를 생성하려면 `AutoClass`를 사용하는 것이 좋습니다. 하지만 특정 모델 파라미터를 보다 세밀하게 제어하고자 하는 사용자는 몇 가지 기본 클래스만으로 커스텀 🤗 Transformers 모델을 생성할 수 있습니다. 이는 🤗 Transformers 모델을 연구, 교육 또는 실험하는 데 관심이 있는 모든 사용자에게 특히 유용할 수 있습니다. 이 가이드에서는 'AutoClass'를 사용하지 않고 커스텀 모델을 만드는 방법에 대해 알아보겠습니다:
+
+- 모델 configuration을 가져오고 사용자 지정합니다.
+- 모델 아키텍처를 생성합니다.
+- 텍스트에 사용할 느리거나 빠른 토큰화기를 만듭니다.
+- 비전 작업을 위한 이미지 프로세서를 생성합니다.
+- 오디오 작업을 위한 특성 추출기를 생성합니다.
+- 멀티모달 작업용 프로세서를 생성합니다.
+
+## Configuration[[configuration]]
+
+[configuration](main_classes/configuration)은 모델의 특정 속성을 나타냅니다. 각 모델 구성에는 서로 다른 속성이 있습니다. 예를 들어, 모든 NLP 모델에는 `hidden_size`, `num_attention_heads`, `num_hidden_layers` 및 `vocab_size` 속성이 공통으로 있습니다. 이러한 속성은 모델을 구성할 attention heads 또는 hidden layers의 수를 지정합니다.
+
+[DistilBERT](model_doc/distilbert) 속성을 검사하기 위해 [`DistilBertConfig`]에 접근하여 자세히 살펴봅니다:
+
+```py
+>>> from transformers import DistilBertConfig
+
+>>> config = DistilBertConfig()
+>>> print(config)
+DistilBertConfig {
+ "activation": "gelu",
+ "attention_dropout": 0.1,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+[`DistilBertConfig`]는 기본 [`DistilBertModel`]을 빌드하는 데 사용되는 모든 기본 속성을 표시합니다. 모든 속성은 커스터마이징이 가능하므로 실험을 위한 공간을 만들 수 있습니다. 예를 들어 기본 모델을 다음과 같이 커스터마이즈할 수 있습니다:
+
+- `activation` 파라미터로 다른 활성화 함수를 사용해 보세요.
+- `attention_dropout` 파라미터를 사용하여 어텐션 확률에 더 높은 드롭아웃 비율을 사용하세요.
+
+```py
+>>> my_config = DistilBertConfig(activation="relu", attention_dropout=0.4)
+>>> print(my_config)
+DistilBertConfig {
+ "activation": "relu",
+ "attention_dropout": 0.4,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+사전 학습된 모델 속성은 [`~PretrainedConfig.from_pretrained`] 함수에서 수정할 수 있습니다:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("distilbert/distilbert-base-uncased", activation="relu", attention_dropout=0.4)
+```
+
+모델 구성이 만족스러우면 [`~PretrainedConfig.save_pretrained`]로 저장할 수 있습니다. 설정 파일은 지정된 작업 경로에 JSON 파일로 저장됩니다:
+
+```py
+>>> my_config.save_pretrained(save_directory="./your_model_save_path")
+```
+
+configuration 파일을 재사용하려면 [`~PretrainedConfig.from_pretrained`]를 사용하여 가져오세요:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/config.json")
+```
+
+
+
+configuration 파일을 딕셔너리로 저장하거나 사용자 정의 configuration 속성과 기본 configuration 속성의 차이점만 저장할 수도 있습니다! 자세한 내용은 [configuration](main_classes/configuration) 문서를 참조하세요.
+
+
+
+## 모델[[model]]
+
+다음 단계는 [모델(model)](main_classes/models)을 만드는 것입니다. 느슨하게 아키텍처라고도 불리는 모델은 각 계층이 수행하는 동작과 발생하는 작업을 정의합니다. configuration의 `num_hidden_layers`와 같은 속성은 아키텍처를 정의하는 데 사용됩니다. 모든 모델은 기본 클래스 [`PreTrainedModel`]과 입력 임베딩 크기 조정 및 셀프 어텐션 헤드 가지 치기와 같은 몇 가지 일반적인 메소드를 공유합니다. 또한 모든 모델은 [`torch.nn.Module`](https://pytorch.org/docs/stable/generated/torch.nn.Module.html), [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) 또는 [`flax.linen.Module`](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html)의 서브클래스이기도 합니다. 즉, 모델은 각 프레임워크의 사용법과 호환됩니다.
+
+
+
+사용자 지정 configuration 속성을 모델에 가져옵니다:
+
+```py
+>>> from transformers import DistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/config.json")
+>>> model = DistilBertModel(my_config)
+```
+
+이제 사전 학습된 가중치 대신 임의의 값을 가진 모델이 생성됩니다. 이 모델을 훈련하기 전까지는 유용하게 사용할 수 없습니다. 훈련은 비용과 시간이 많이 소요되는 프로세스입니다. 일반적으로 훈련에 필요한 리소스의 일부만 사용하면서 더 나은 결과를 더 빨리 얻으려면 사전 훈련된 모델을 사용하는 것이 좋습니다.
+
+사전 학습된 모델을 [`~PreTrainedModel.from_pretrained`]로 생성합니다:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+🤗 Transformers에서 제공한 모델의 사전 학습된 가중치를 사용하는 경우 기본 모델 configuration을 자동으로 불러옵니다. 그러나 원하는 경우 기본 모델 configuration 속성의 일부 또는 전부를 사용자 지정으로 바꿀 수 있습니다:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+사용자 지정 configuration 속성을 모델에 불러옵니다:
+
+```py
+>>> from transformers import TFDistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+>>> tf_model = TFDistilBertModel(my_config)
+```
+
+이제 사전 학습된 가중치 대신 임의의 값을 가진 모델이 생성됩니다. 이 모델을 훈련하기 전까지는 유용하게 사용할 수 없습니다. 훈련은 비용과 시간이 많이 소요되는 프로세스입니다. 일반적으로 훈련에 필요한 리소스의 일부만 사용하면서 더 나은 결과를 더 빨리 얻으려면 사전 훈련된 모델을 사용하는 것이 좋습니다.
+
+사전 학습된 모델을 [`~TFPreTrainedModel.from_pretrained`]로 생성합니다:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+🤗 Transformers에서 제공한 모델의 사전 학습된 가중치를 사용하는 경우 기본 모델 configuration을 자동으로 불러옵니다. 그러나 원하는 경우 기본 모델 configuration 속성의 일부 또는 전부를 사용자 지정으로 바꿀 수 있습니다:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+
+### 모델 헤드[[model-heads]]
+
+이 시점에서 *은닉 상태(hidden state)*를 출력하는 기본 DistilBERT 모델을 갖게 됩니다. 은닉 상태는 최종 출력을 생성하기 위해 모델 헤드에 입력으로 전달됩니다. 🤗 Transformers는 모델이 해당 작업을 지원하는 한 각 작업마다 다른 모델 헤드를 제공합니다(즉, 번역과 같은 시퀀스 간 작업에는 DistilBERT를 사용할 수 없음).
+
+
+
+예를 들어, [`DistilBertForSequenceClassification`]은 시퀀스 분류 헤드가 있는 기본 DistilBERT 모델입니다. 시퀀스 분류 헤드는 풀링된 출력 위에 있는 선형 레이어입니다.
+
+```py
+>>> from transformers import DistilBertForSequenceClassification
+
+>>> model = DistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+다른 모델 헤드로 전환하여 이 체크포인트를 다른 작업에 쉽게 재사용할 수 있습니다. 질의응답 작업의 경우, [`DistilBertForQuestionAnswering`] 모델 헤드를 사용할 수 있습니다. 질의응답 헤드는 숨겨진 상태 출력 위에 선형 레이어가 있다는 점을 제외하면 시퀀스 분류 헤드와 유사합니다.
+
+```py
+>>> from transformers import DistilBertForQuestionAnswering
+
+>>> model = DistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+예를 들어, [`TFDistilBertForSequenceClassification`]은 시퀀스 분류 헤드가 있는 기본 DistilBERT 모델입니다. 시퀀스 분류 헤드는 풀링된 출력 위에 있는 선형 레이어입니다.
+
+```py
+>>> from transformers import TFDistilBertForSequenceClassification
+
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+다른 모델 헤드로 전환하여 이 체크포인트를 다른 작업에 쉽게 재사용할 수 있습니다. 질의응답 작업의 경우, [`TFDistilBertForQuestionAnswering`] 모델 헤드를 사용할 수 있습니다. 질의응답 헤드는 숨겨진 상태 출력 위에 선형 레이어가 있다는 점을 제외하면 시퀀스 분류 헤드와 유사합니다.
+
+```py
+>>> from transformers import TFDistilBertForQuestionAnswering
+
+>>> tf_model = TFDistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+## 토크나이저[[tokenizer]]
+
+텍스트 데이터에 모델을 사용하기 전에 마지막으로 필요한 기본 클래스는 원시 텍스트를 텐서로 변환하는 [토크나이저](main_classes/tokenizer)입니다. 🤗 Transformers에 사용할 수 있는 토크나이저는 두 가지 유형이 있습니다:
+
+- [`PreTrainedTokenizer`]: 파이썬으로 구현된 토크나이저입니다.
+- [`PreTrainedTokenizerFast`]: Rust 기반 [🤗 Tokenizer](https://huggingface.co/docs/tokenizers/python/latest/) 라이브러리로 만들어진 토크나이저입니다. 이 토크나이저는 Rust로 구현되어 배치 토큰화에서 특히 빠릅니다. 빠른 토크나이저는 토큰을 원래 단어나 문자에 매핑하는 *오프셋 매핑*과 같은 추가 메소드도 제공합니다.
+두 토크나이저 모두 인코딩 및 디코딩, 새 토큰 추가, 특수 토큰 관리와 같은 일반적인 방법을 지원합니다.
+
+
+
+모든 모델이 빠른 토크나이저를 지원하는 것은 아닙니다. 이 [표](index#supported-frameworks)에서 모델의 빠른 토크나이저 지원 여부를 확인하세요.
+
+
+
+토크나이저를 직접 학습한 경우, *어휘(vocabulary)* 파일에서 토크나이저를 만들 수 있습니다:
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> my_tokenizer = DistilBertTokenizer(vocab_file="my_vocab_file.txt", do_lower_case=False, padding_side="left")
+```
+
+사용자 지정 토크나이저의 어휘는 사전 학습된 모델의 토크나이저에서 생성된 어휘와 다를 수 있다는 점을 기억하는 것이 중요합니다. 사전 학습된 모델을 사용하는 경우 사전 학습된 모델의 어휘를 사용해야 하며, 그렇지 않으면 입력이 의미를 갖지 못합니다. [`DistilBertTokenizer`] 클래스를 사용하여 사전 학습된 모델의 어휘로 토크나이저를 생성합니다:
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> slow_tokenizer = DistilBertTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+[`DistilBertTokenizerFast`] 클래스로 빠른 토크나이저를 생성합니다:
+
+```py
+>>> from transformers import DistilBertTokenizerFast
+
+>>> fast_tokenizer = DistilBertTokenizerFast.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+[`AutoTokenizer`]는 기본적으로 빠른 토크나이저를 가져오려고 합니다. 이 동작을 비활성화하려면 `from_pretrained`에서 `use_fast=False`를 설정하면 됩니다.
+
+
+
+## 이미지 프로세서[[image-processor]]
+
+이미지 프로세서(image processor)는 비전 입력을 처리합니다. 기본 [`~image_processing_utils.ImageProcessingMixin`] 클래스에서 상속합니다.
+
+사용하려면 사용 중인 모델과 연결된 이미지 프로세서를 생성합니다. 예를 들어, 이미지 분류에 [ViT](model_doc/vit)를 사용하는 경우 기본 [`ViTImageProcessor`]를 생성합니다:
+
+```py
+>>> from transformers import ViTImageProcessor
+
+>>> vit_extractor = ViTImageProcessor()
+>>> print(vit_extractor)
+ViTImageProcessor {
+ "do_normalize": true,
+ "do_resize": true,
+ "feature_extractor_type": "ViTImageProcessor",
+ "image_mean": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": 2,
+ "size": 224
+}
+```
+
+
+
+사용자 지정을 원하지 않는 경우 `from_pretrained` 메소드를 사용하여 모델의 기본 이미지 프로세서 매개변수를 불러오면 됩니다.
+
+
+
+사용자 지정 이미지 프로세서를 생성하려면 [`ViTImageProcessor`] 파라미터를 수정합니다:
+
+```py
+>>> from transformers import ViTImageProcessor
+
+>>> my_vit_extractor = ViTImageProcessor(resample="PIL.Image.BOX", do_normalize=False, image_mean=[0.3, 0.3, 0.3])
+>>> print(my_vit_extractor)
+ViTImageProcessor {
+ "do_normalize": false,
+ "do_resize": true,
+ "feature_extractor_type": "ViTImageProcessor",
+ "image_mean": [
+ 0.3,
+ 0.3,
+ 0.3
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": "PIL.Image.BOX",
+ "size": 224
+}
+```
+
+## 특성 추출기[[feature-extractor]]
+
+특성 추출기(feature extractor)는 오디오 입력을 처리합니다. 기본 [`~feature_extraction_utils.FeatureExtractionMixin`] 클래스에서 상속되며, 오디오 입력을 처리하기 위해 [`SequenceFeatureExtractor`] 클래스에서 상속할 수도 있습니다.
+
+사용하려면 사용 중인 모델과 연결된 특성 추출기를 생성합니다. 예를 들어, 오디오 분류에 [Wav2Vec2](model_doc/wav2vec2)를 사용하는 경우 기본 [`Wav2Vec2FeatureExtractor`]를 생성합니다:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> w2v2_extractor = Wav2Vec2FeatureExtractor()
+>>> print(w2v2_extractor)
+Wav2Vec2FeatureExtractor {
+ "do_normalize": true,
+ "feature_extractor_type": "Wav2Vec2FeatureExtractor",
+ "feature_size": 1,
+ "padding_side": "right",
+ "padding_value": 0.0,
+ "return_attention_mask": false,
+ "sampling_rate": 16000
+}
+```
+
+
+
+사용자 지정이 필요하지 않은 경우 `from_pretrained` 메소드를 사용하여 모델의 기본 특성 추출기 ㅁ개변수를 불러 오면 됩니다.
+
+
+
+사용자 지정 특성 추출기를 만들려면 [`Wav2Vec2FeatureExtractor`] 매개변수를 수정합니다:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> w2v2_extractor = Wav2Vec2FeatureExtractor(sampling_rate=8000, do_normalize=False)
+>>> print(w2v2_extractor)
+Wav2Vec2FeatureExtractor {
+ "do_normalize": false,
+ "feature_extractor_type": "Wav2Vec2FeatureExtractor",
+ "feature_size": 1,
+ "padding_side": "right",
+ "padding_value": 0.0,
+ "return_attention_mask": false,
+ "sampling_rate": 8000
+}
+```
+
+
+## 프로세서[[processor]]
+
+멀티모달 작업을 지원하는 모델의 경우, 🤗 Transformers는 특성 추출기 및 토크나이저와 같은 처리 클래스를 단일 객체로 편리하게 래핑하는 프로세서 클래스를 제공합니다. 예를 들어, 자동 음성 인식 작업(Automatic Speech Recognition task (ASR))에 [`Wav2Vec2Processor`]를 사용한다고 가정해 보겠습니다. 자동 음성 인식 작업은 오디오를 텍스트로 변환하므로 특성 추출기와 토크나이저가 필요합니다.
+
+오디오 입력을 처리할 특성 추출기를 만듭니다:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> feature_extractor = Wav2Vec2FeatureExtractor(padding_value=1.0, do_normalize=True)
+```
+
+텍스트 입력을 처리할 토크나이저를 만듭니다:
+
+```py
+>>> from transformers import Wav2Vec2CTCTokenizer
+
+>>> tokenizer = Wav2Vec2CTCTokenizer(vocab_file="my_vocab_file.txt")
+```
+
+[`Wav2Vec2Processor`]에서 특성 추출기와 토크나이저를 결합합니다:
+
+```py
+>>> from transformers import Wav2Vec2Processor
+
+>>> processor = Wav2Vec2Processor(feature_extractor=feature_extractor, tokenizer=tokenizer)
+```
+
+configuration과 모델이라는 두 가지 기본 클래스와 추가 전처리 클래스(토크나이저, 이미지 프로세서, 특성 추출기 또는 프로세서)를 사용하면 🤗 Transformers에서 지원하는 모든 모델을 만들 수 있습니다. 이러한 각 기본 클래스는 구성이 가능하므로 원하는 특정 속성을 사용할 수 있습니다. 학습을 위해 모델을 쉽게 설정하거나 기존의 사전 학습된 모델을 수정하여 미세 조정할 수 있습니다.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/custom_models.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/custom_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..cb67a535b47d41453e2b5d27fcc67b89a7ab7407
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/custom_models.md
@@ -0,0 +1,346 @@
+
+
+# 사용자 정의 모델 공유하기[[sharing-custom-models]]
+
+🤗 Transformers 라이브러리는 쉽게 확장할 수 있도록 설계되었습니다.
+모든 모델은 추상화 없이 저장소의 지정된 하위 폴더에 완전히 코딩되어 있으므로, 손쉽게 모델링 파일을 복사하고 필요에 따라 조정할 수 있습니다.
+
+완전히 새로운 모델을 만드는 경우에는 처음부터 시작하는 것이 더 쉬울 수 있습니다.
+이 튜토리얼에서는 Transformers 내에서 사용할 수 있도록 사용자 정의 모델과 구성을 작성하는 방법과
+🤗 Transformers 라이브러리에 없는 경우에도 누구나 사용할 수 있도록 (의존성과 함께) 커뮤니티에 공유하는 방법을 배울 수 있습니다.
+
+[timm 라이브러리](https://github.com/rwightman/pytorch-image-models)의 ResNet 클래스를 [`PreTrainedModel`]로 래핑한 ResNet 모델을 예로 모든 것을 설명합니다.
+
+## 사용자 정의 구성 작성하기[[writing-a-custom-configuration]]
+
+모델에 들어가기 전에 먼저 구성을 작성해보도록 하겠습니다.
+모델의 `configuration`은 모델을 만들기 위해 필요한 모든 중요한 것들을 포함하고 있는 객체입니다.
+다음 섹션에서 볼 수 있듯이, 모델은 `config`를 사용해서만 초기화할 수 있기 때문에 완벽한 구성이 필요합니다.
+
+아래 예시에서는 ResNet 클래스의 인수(argument)를 조정해보겠습니다.
+다른 구성은 가능한 ResNet 중 다른 유형을 제공합니다.
+그런 다음 몇 가지 유효성을 확인한 후 해당 인수를 저장합니다.
+
+```python
+from transformers import PretrainedConfig
+from typing import List
+
+
+class ResnetConfig(PretrainedConfig):
+ model_type = "resnet"
+
+ def __init__(
+ self,
+ block_type="bottleneck",
+ layers: List[int] = [3, 4, 6, 3],
+ num_classes: int = 1000,
+ input_channels: int = 3,
+ cardinality: int = 1,
+ base_width: int = 64,
+ stem_width: int = 64,
+ stem_type: str = "",
+ avg_down: bool = False,
+ **kwargs,
+ ):
+ if block_type not in ["basic", "bottleneck"]:
+ raise ValueError(f"`block_type` must be 'basic' or bottleneck', got {block_type}.")
+ if stem_type not in ["", "deep", "deep-tiered"]:
+ raise ValueError(f"`stem_type` must be '', 'deep' or 'deep-tiered', got {stem_type}.")
+
+ self.block_type = block_type
+ self.layers = layers
+ self.num_classes = num_classes
+ self.input_channels = input_channels
+ self.cardinality = cardinality
+ self.base_width = base_width
+ self.stem_width = stem_width
+ self.stem_type = stem_type
+ self.avg_down = avg_down
+ super().__init__(**kwargs)
+```
+
+사용자 정의 `configuration`을 작성할 때 기억해야 할 세 가지 중요한 사항은 다음과 같습니다:
+- `PretrainedConfig`을 상속해야 합니다.
+- `PretrainedConfig`의 `__init__`은 모든 kwargs를 허용해야 하고,
+- 이러한 `kwargs`는 상위 클래스 `__init__`에 전달되어야 합니다.
+
+상속은 🤗 Transformers 라이브러리에서 모든 기능을 가져오는 것입니다.
+이러한 점으로부터 비롯되는 두 가지 제약 조건은 `PretrainedConfig`에 설정하는 것보다 더 많은 필드가 있습니다.
+`from_pretrained` 메서드로 구성을 다시 로드할 때 해당 필드는 구성에서 수락한 후 상위 클래스로 보내야 합니다.
+
+모델을 auto 클래스에 등록하지 않는 한, `configuration`에서 `model_type`을 정의(여기서 `model_type="resnet"`)하는 것은 필수 사항이 아닙니다 (마지막 섹션 참조).
+
+이렇게 하면 라이브러리의 다른 모델 구성과 마찬가지로 구성을 쉽게 만들고 저장할 수 있습니다.
+다음은 resnet50d 구성을 생성하고 저장하는 방법입니다:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d_config.save_pretrained("custom-resnet")
+```
+
+이렇게 하면 `custom-resnet` 폴더 안에 `config.json`이라는 파일이 저장됩니다.
+그런 다음 `from_pretrained` 메서드를 사용하여 구성을 다시 로드할 수 있습니다.
+
+```py
+resnet50d_config = ResnetConfig.from_pretrained("custom-resnet")
+```
+
+구성을 Hub에 직접 업로드하기 위해 [`PretrainedConfig`] 클래스의 [`~PretrainedConfig.push_to_hub`]와 같은 다른 메서드를 사용할 수 있습니다.
+
+
+## 사용자 정의 모델 작성하기[[writing-a-custom-model]]
+
+이제 ResNet 구성이 있으므로 모델을 작성할 수 있습니다.
+실제로는 두 개를 작성할 것입니다. 하나는 이미지 배치에서 hidden features를 추출하는 것([`BertModel`]과 같이), 다른 하나는 이미지 분류에 적합한 것입니다([`BertForSequenceClassification`]과 같이).
+
+이전에 언급했듯이 이 예제에서는 단순하게 하기 위해 모델의 느슨한 래퍼(loose wrapper)만 작성할 것입니다.
+이 클래스를 작성하기 전에 블록 유형과 실제 블록 클래스 간의 매핑 작업만 하면 됩니다.
+그런 다음 `ResNet` 클래스로 전달되어 `configuration`을 통해 모델이 선언됩니다:
+
+```py
+from transformers import PreTrainedModel
+from timm.models.resnet import BasicBlock, Bottleneck, ResNet
+from .configuration_resnet import ResnetConfig
+
+
+BLOCK_MAPPING = {"basic": BasicBlock, "bottleneck": Bottleneck}
+
+
+class ResnetModel(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor):
+ return self.model.forward_features(tensor)
+```
+
+이미지 분류 모델을 만들기 위해서는 forward 메소드만 변경하면 됩니다:
+
+```py
+import torch
+
+
+class ResnetModelForImageClassification(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor, labels=None):
+ logits = self.model(tensor)
+ if labels is not None:
+ loss = torch.nn.functional.cross_entropy(logits, labels)
+ return {"loss": loss, "logits": logits}
+ return {"logits": logits}
+```
+
+두 경우 모두 `PreTrainedModel`를 상속받고, `config`를 통해 상위 클래스 초기화를 호출하다는 점을 기억하세요 (일반적인 `torch.nn.Module`을 작성할 때와 비슷함).
+모델을 auto 클래스에 등록하고 싶은 경우에는 `config_class`를 설정하는 부분이 필수입니다 (마지막 섹션 참조).
+
+
+
+라이브러리에 존재하는 모델과 굉장히 유사하다면, 모델을 생성할 때 구성을 참조해 재사용할 수 있습니다.
+
+
+
+원하는 것을 모델이 반환하도록 할 수 있지만, `ResnetModelForImageClassification`에서 했던 것 처럼
+레이블을 통과시켰을 때 손실과 함께 사전 형태로 반환하는 것이 [`Trainer`] 클래스 내에서 직접 모델을 사용하기에 유용합니다.
+자신만의 학습 루프 또는 다른 학습 라이브러리를 사용할 계획이라면 다른 출력 형식을 사용해도 좋습니다.
+
+이제 모델 클래스가 있으므로 하나 생성해 보겠습니다:
+
+```py
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+```
+
+다시 말하지만, [`~PreTrainedModel.save_pretrained`]또는 [`~PreTrainedModel.push_to_hub`]처럼 [`PreTrainedModel`]에 속하는 모든 메소드를 사용할 수 있습니다.
+다음 섹션에서 두 번째 메소드를 사용해 모델 코드와 모델 가중치를 업로드하는 방법을 살펴보겠습니다.
+먼저, 모델 내부에 사전 훈련된 가중치를 로드해 보겠습니다.
+
+이 예제를 활용할 때는, 사용자 정의 모델을 자신만의 데이터로 학습시킬 것입니다.
+이 튜토리얼에서는 빠르게 진행하기 위해 사전 훈련된 resnet50d를 사용하겠습니다.
+아래 모델은 resnet50d의 래퍼이기 때문에, 가중치를 쉽게 로드할 수 있습니다.
+
+
+```py
+import timm
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+이제 [`~PreTrainedModel.save_pretrained`] 또는 [`~PreTrainedModel.push_to_hub`]를 사용할 때 모델 코드가 저장되는지 확인해봅시다.
+
+## Hub로 코드 업로드하기[[sending-the-code-to-the-hub]]
+
+
+
+이 API는 실험적이며 다음 릴리스에서 약간의 변경 사항이 있을 수 있습니다.
+
+
+
+먼저 모델이 `.py` 파일에 완전히 정의되어 있는지 확인하세요.
+모든 파일이 동일한 작업 경로에 있기 때문에 상대경로 임포트(relative import)에 의존할 수 있습니다 (transformers에서는 이 기능에 대한 하위 모듈을 지원하지 않습니다).
+이 예시에서는 작업 경로 안의 `resnet_model`에서 `modeling_resnet.py` 파일과 `configuration_resnet.py` 파일을 정의합니다.
+구성 파일에는 `ResnetConfig`에 대한 코드가 있고 모델링 파일에는 `ResnetModel` 및 `ResnetModelForImageClassification`에 대한 코드가 있습니다.
+
+```
+.
+└── resnet_model
+ ├── __init__.py
+ ├── configuration_resnet.py
+ └── modeling_resnet.py
+```
+
+Python이 `resnet_model`을 모듈로 사용할 수 있도록 감지하는 목적이기 때문에 `__init__.py`는 비어 있을 수 있습니다.
+
+
+
+라이브러리에서 모델링 파일을 복사하는 경우,
+모든 파일 상단에 있는 상대 경로 임포트(relative import) 부분을 `transformers` 패키지에서 임포트 하도록 변경해야 합니다.
+
+
+
+기존 구성이나 모델을 재사용(또는 서브 클래스화)할 수 있습니다.
+
+커뮤니티에 모델을 공유하기 위해서는 다음 단계를 따라야 합니다:
+먼저, 새로 만든 파일에 ResNet 모델과 구성을 임포트합니다:
+
+```py
+from resnet_model.configuration_resnet import ResnetConfig
+from resnet_model.modeling_resnet import ResnetModel, ResnetModelForImageClassification
+```
+
+다음으로 `save_pretrained` 메소드를 사용해 해당 객체의 코드 파일을 복사하고,
+복사한 파일을 Auto 클래스로 등록하고(모델인 경우) 실행합니다:
+
+```py
+ResnetConfig.register_for_auto_class()
+ResnetModel.register_for_auto_class("AutoModel")
+ResnetModelForImageClassification.register_for_auto_class("AutoModelForImageClassification")
+```
+
+`configuration`에 대한 auto 클래스를 지정할 필요는 없지만(`configuration` 관련 auto 클래스는 AutoConfig 클래스 하나만 있음), 모델의 경우에는 지정해야 합니다.
+사용자 지정 모델은 다양한 작업에 적합할 수 있으므로, 모델에 맞는 auto 클래스를 지정해야 합니다.
+
+다음으로, 이전에 작업했던 것과 마찬가지로 구성과 모델을 작성합니다:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+이제 모델을 Hub로 업로드하기 위해 로그인 상태인지 확인하세요.
+터미널에서 다음 코드를 실행해 확인할 수 있습니다:
+
+```bash
+huggingface-cli login
+```
+
+주피터 노트북의 경우에는 다음과 같습니다:
+
+```py
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+그런 다음 이렇게 자신의 네임스페이스(또는 자신이 속한 조직)에 업로드할 수 있습니다:
+```py
+resnet50d.push_to_hub("custom-resnet50d")
+```
+
+On top of the modeling weights and the configuration in json format, this also copied the modeling and
+configuration `.py` files in the folder `custom-resnet50d` and uploaded the result to the Hub. You can check the result
+in this [model repo](https://huggingface.co/sgugger/custom-resnet50d).
+json 형식의 모델링 가중치와 구성 외에도 `custom-resnet50d` 폴더 안의 모델링과 구성 `.py` 파일을 복사하해 Hub에 업로드합니다.
+[모델 저장소](https://huggingface.co/sgugger/custom-resnet50d)에서 결과를 확인할 수 있습니다.
+
+[sharing tutorial](model_sharing) 문서의 `push_to_hub` 메소드에서 자세한 내용을 확인할 수 있습니다.
+
+
+## 사용자 정의 코드로 모델 사용하기[[using-a-model-with-custom-code]]
+
+auto 클래스와 `from_pretrained` 메소드를 사용하여 사용자 지정 코드 파일과 함께 모든 구성, 모델, 토크나이저를 사용할 수 있습니다.
+Hub에 업로드된 모든 파일 및 코드는 멜웨어가 있는지 검사되지만 (자세한 내용은 [Hub 보안](https://huggingface.co/docs/hub/security#malware-scanning) 설명 참조),
+자신의 컴퓨터에서 모델 코드와 작성자가 악성 코드를 실행하지 않는지 확인해야 합니다.
+사용자 정의 코드로 모델을 사용하려면 `trust_remote_code=True`로 설정하세요:
+
+```py
+from transformers import AutoModelForImageClassification
+
+model = AutoModelForImageClassification.from_pretrained("sgugger/custom-resnet50d", trust_remote_code=True)
+```
+
+모델 작성자가 악의적으로 코드를 업데이트하지 않았다는 점을 확인하기 위해, 커밋 해시(commit hash)를 `revision`으로 전달하는 것도 강력히 권장됩니다 (모델 작성자를 완전히 신뢰하지 않는 경우).
+
+```py
+commit_hash = "ed94a7c6247d8aedce4647f00f20de6875b5b292"
+model = AutoModelForImageClassification.from_pretrained(
+ "sgugger/custom-resnet50d", trust_remote_code=True, revision=commit_hash
+)
+```
+
+Hub에서 모델 저장소의 커밋 기록을 찾아볼 때, 모든 커밋의 커밋 해시를 쉽게 복사할 수 있는 버튼이 있습니다.
+
+## 사용자 정의 코드로 만든 모델을 auto 클래스로 등록하기[[registering-a-model-with-custom-code-to-the-auto-classes]]
+
+🤗 Transformers를 상속하는 라이브러리를 작성하는 경우 사용자 정의 모델을 auto 클래스에 추가할 수 있습니다.
+사용자 정의 모델을 사용하기 위해 해당 라이브러리를 임포트해야 하기 때문에, 이는 Hub로 코드를 업로드하는 것과 다릅니다 (Hub에서 자동적으로 모델 코드를 다운로드 하는 것과 반대).
+
+구성에 기존 모델 유형과 다른 `model_type` 속성이 있고 모델 클래스에 올바른 `config_class` 속성이 있는 한,
+다음과 같이 auto 클래스에 추가할 수 있습니다:
+
+```py
+from transformers import AutoConfig, AutoModel, AutoModelForImageClassification
+
+AutoConfig.register("resnet", ResnetConfig)
+AutoModel.register(ResnetConfig, ResnetModel)
+AutoModelForImageClassification.register(ResnetConfig, ResnetModelForImageClassification)
+```
+
+사용자 정의 구성을 [`AutoConfig`]에 등록할 때 사용되는 첫 번째 인수는 사용자 정의 구성의 `model_type`과 일치해야 합니다.
+또한, 사용자 정의 모델을 auto 클래스에 등록할 때 사용되는 첫 번째 인수는 해당 모델의 `config_class`와 일치해야 합니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/debugging.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/debugging.md
new file mode 100644
index 0000000000000000000000000000000000000000..24b2c7b04b509d9301003a3911dbb0b0e324eedf
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/debugging.md
@@ -0,0 +1,306 @@
+
+
+# 디버깅 [[debugging]]
+
+## Multi-GPU 네트워크 문제 디버그 [[multigpu-network-issues-debug]]
+
+`DistributedDataParallel` 및 다중 GPU를 사용하여 훈련하거나 추론할 때, 프로세스 및/또는 노드 간의 상호 통신 문제가 발생하는 경우, 다음 스크립트를 사용하여 네트워크 문제를 진단할 수 있습니다.
+
+```bash
+wget https://raw.githubusercontent.com/huggingface/transformers/main/scripts/distributed/torch-distributed-gpu-test.py
+```
+
+예를 들어, 2개의 GPU가 상호 작용하는 방식을 테스트하려면 다음을 실행하세요:
+
+```bash
+python -m torch.distributed.run --nproc_per_node 2 --nnodes 1 torch-distributed-gpu-test.py
+```
+두 프로세스가 서로 통신하고 GPU 메모리를 할당하는 경우, 각각 "OK" 상태를 출력합니다.
+
+더 많은 GPU 또는 노드의 경우 스크립트의 인수를 조정하면 됩니다.
+
+진단 스크립트 내에서 더 많은 세부 정보와 SLURM 환경에서 실행하는 방법에 대한 레시피를 찾을 수 있습니다.
+
+추가적인 디버그 수준은 다음과 같이 `NCCL_DEBUG=INFO` 환경 변수를 추가하는 것입니다:
+
+```bash
+NCCL_DEBUG=INFO python -m torch.distributed.run --nproc_per_node 2 --nnodes 1 torch-distributed-gpu-test.py
+```
+
+이렇게 하면 NCCL 관련 디버그 정보가 많이 출력되며, 문제가 보고된 경우에는 인터넷에서 검색할 수 있습니다. 또는 출력을 해석하는 방법을 잘 모르는 경우 로그 파일을 이슈에 공유할 수 있습니다.
+
+
+
+## 언더플로 및 오버플로 감지 [[underflow-and-overflow-detection]]
+
+
+
+
+이 기능은 현재 PyTorch에서만 사용할 수 있습니다.
+
+
+
+
+
+다중 GPU 훈련을 위해서는 DDP (`torch.distributed.launch`)가 필요합니다.
+
+
+
+
+
+이 기능은 `nn.Module`을 기반으로 하는 모델과 함께 사용할 수 있습니다.
+
+
+
+`loss=NaN`이 나타나거나 모델이 `inf` 또는 `nan`으로 인해 다른 이상한 동작을 하는 경우, 언더플로 또는 오버플로의 첫 번째 발생 위치와 그 원인을 파악해야 합니다. 다행히도 이를 자동으로 감지하는 특수 모듈을 활성화하여 쉽게 알아낼 수 있습니다.
+
+[`Trainer`]를 사용하는 경우, 다음을 기존의 명령줄 인수에 추가하면 됩니다.
+
+```bash
+--debug underflow_overflow
+```
+또는 [`TrainingArguments`] 객체를 생성할 때 `debug="underflow_overflow"`를 전달합니다.
+
+자체 훈련 루프나 다른 Trainer를 사용하는 경우, 다음과 같이 수행할 수 있습니다.
+
+```python
+from transformers.debug_utils import DebugUnderflowOverflow
+
+debug_overflow = DebugUnderflowOverflow(model)
+```
+
+[`~debug_utils.DebugUnderflowOverflow`]는 모델에 후크를 삽입하여 각 forward 호출 직후에 입력 및 출력 변수 및 해당 모듈의 가중치를 테스트합니다. 활성화나 가중치의 최소한 하나의 요소에서 `inf` 또는 `nan`이 감지되면 프로그램이 어설트되고 다음과 같은 보고서가 출력됩니다. (이 예제는 fp16 혼합 정밀도에서 `google/mt5-small`에서 캡처된 것입니다):
+
+```
+Detected inf/nan during batch_number=0
+Last 21 forward frames:
+abs min abs max metadata
+ encoder.block.1.layer.1.DenseReluDense.dropout Dropout
+0.00e+00 2.57e+02 input[0]
+0.00e+00 2.85e+02 output
+[...]
+ encoder.block.2.layer.0 T5LayerSelfAttention
+6.78e-04 3.15e+03 input[0]
+2.65e-04 3.42e+03 output[0]
+ None output[1]
+2.25e-01 1.00e+04 output[2]
+ encoder.block.2.layer.1.layer_norm T5LayerNorm
+8.69e-02 4.18e-01 weight
+2.65e-04 3.42e+03 input[0]
+1.79e-06 4.65e+00 output
+ encoder.block.2.layer.1.DenseReluDense.wi_0 Linear
+2.17e-07 4.50e+00 weight
+1.79e-06 4.65e+00 input[0]
+2.68e-06 3.70e+01 output
+ encoder.block.2.layer.1.DenseReluDense.wi_1 Linear
+8.08e-07 2.66e+01 weight
+1.79e-06 4.65e+00 input[0]
+1.27e-04 2.37e+02 output
+ encoder.block.2.layer.1.DenseReluDense.dropout Dropout
+0.00e+00 8.76e+03 input[0]
+0.00e+00 9.74e+03 output
+ encoder.block.2.layer.1.DenseReluDense.wo Linear
+1.01e-06 6.44e+00 weight
+0.00e+00 9.74e+03 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.DenseReluDense T5DenseGatedGeluDense
+1.79e-06 4.65e+00 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.dropout Dropout
+3.18e-04 6.27e+04 input[0]
+0.00e+00 inf output
+```
+
+예제 출력은 간략성을 위해 중간 부분이 잘려 있습니다.
+
+두 번째 열은 절대적으로 가장 큰 요소의 값이며, 따라서 마지막 몇 개의 프레임을 자세히 살펴보면 입력과 출력이 `1e4` 범위에 있음을 알 수 있습니다. 따라서 이 훈련은 `fp16` 혼합 정밀도로 수행될 때 가장 마지막 단계에서 오버플로우가 발생했습니다 (`fp16`에서 `inf` 이전의 가장 큰 숫자는 `64e3`입니다). `fp16` 아래에서 오버플로우를 피하기 위해서는 활성화는 `1e4`보다 훨씬 작아야 합니다. 왜냐하면 `1e4 * 1e4 = 1e8`이기 때문에 큰 활성화와의 행렬 곱은 수치적인 오버플로우 조건으로 이어질 것입니다.
+
+추적의 맨 처음에서 어느 배치 번호에서 문제가 발생했는지 알 수 있습니다 (여기서 `Detected inf/nan during batch_number=0`은 문제가 첫 번째 배치에서 발생했음을 의미합니다).
+
+각 보고된 프레임은 해당 프레임이 보고하는 해당 모듈에 대한 완전한 항목을 선언하며, 이 프레임만 살펴보면 다음과 같습니다.
+
+```
+ encoder.block.2.layer.1.layer_norm T5LayerNorm
+8.69e-02 4.18e-01 weight
+2.65e-04 3.42e+03 input[0]
+1.79e-06 4.65e+00 output
+```
+
+여기서 `encoder.block.2.layer.1.layer_norm`은 인코더의 두 번째 블록의 첫 번째 레이어에 대한 레이어 정규화를 의미하며, `forward`의 특정 호출은 `T5LayerNorm`입니다.
+
+이 보고서의 마지막 몇 개 프레임을 살펴보겠습니다:
+
+```
+Detected inf/nan during batch_number=0
+Last 21 forward frames:
+abs min abs max metadata
+[...]
+ encoder.block.2.layer.1.DenseReluDense.wi_0 Linear
+2.17e-07 4.50e+00 weight
+1.79e-06 4.65e+00 input[0]
+2.68e-06 3.70e+01 output
+ encoder.block.2.layer.1.DenseReluDense.wi_1 Linear
+8.08e-07 2.66e+01 weight
+1.79e-06 4.65e+00 input[0]
+1.27e-04 2.37e+02 output
+ encoder.block.2.layer.1.DenseReluDense.wo Linear
+1.01e-06 6.44e+00 weight
+0.00e+00 9.74e+03 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.DenseReluDense T5DenseGatedGeluDense
+1.79e-06 4.65e+00 input[0]
+3.18e-04 6.27e+04 output
+ encoder.block.2.layer.1.dropout Dropout
+3.18e-04 6.27e+04 input[0]
+0.00e+00 inf output
+```
+
+마지막 프레임은 `Dropout.forward` 함수에 대한 보고입니다. 첫 번째 항목은 유일한 입력을 나타내고 두 번째 항목은 유일한 출력을 나타냅니다. 이 함수가 `DenseReluDense` 클래스 내부의 `dropout` 속성에서 호출된 것을 볼 수 있습니다. 이는 첫 번째 레이어의 두 번째 블록에서 첫 번째 배치 중에 발생했다는 것을 알 수 있습니다. 마지막으로, 절대적으로 가장 큰 입력 요소는 `6.27e+04`이고 출력도 마찬가지로 `inf`입니다.
+
+여기에서는 `T5DenseGatedGeluDense.forward`가 출력 활성화를 생성하는데, 절대적으로 가장 큰 값이 약 62.7K인 것을 볼 수 있습니다. 이 값은 fp16의 최대 제한인 64K에 매우 근접합니다. 다음 프레임에서는 일부 요소를 0으로 만든 후 가중치를 재정규화하는 `Dropout`이 있습니다. 이로 인해 절대 최대값이 64K를 초과하고 오버플로우(`inf`)가 발생합니다.
+
+보시다시피, fp16 숫자의 경우 숫자가 매우 커질 때 이전 프레임을 살펴보아야 합니다.
+
+보고서를 `models/t5/modeling_t5.py`의 코드와 일치시켜 보겠습니다.
+
+```python
+class T5DenseGatedGeluDense(nn.Module):
+ def __init__(self, config):
+ super().__init__()
+ self.wi_0 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wi_1 = nn.Linear(config.d_model, config.d_ff, bias=False)
+ self.wo = nn.Linear(config.d_ff, config.d_model, bias=False)
+ self.dropout = nn.Dropout(config.dropout_rate)
+ self.gelu_act = ACT2FN["gelu_new"]
+
+ def forward(self, hidden_states):
+ hidden_gelu = self.gelu_act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+```
+
+이제 `dropout` 호출과 이전의 모든 호출을 쉽게 확인할 수 있습니다.
+
+감지는 `forward` 후크에서 발생하므로, 이러한 보고서는 각 `forward`가 반환된 직후에 즉시 출력됩니다.
+
+전체 보고서로 돌아가서 문제에 대한 조치 및 수정을 하려면, 숫자가 증가하기 시작한 몇 개의 프레임 위로 이동해서 여기서 `fp32` 모드로 전환해야 합니다. 이렇게 해야 숫자가 곱해지거나 합쳐질 때 오버플로우되지 않을 가능성이 높습니다. 물론 다른 해결책도 있을 수 있습니다. 예를 들어, `amp`가 활성화된 경우 일시적으로 끄고 원래의 `forward`를 도우미 래퍼로 이동한 후 다음과 같이 할 수 있습니다:
+
+```python
+def _forward(self, hidden_states):
+ hidden_gelu = self.gelu_act(self.wi_0(hidden_states))
+ hidden_linear = self.wi_1(hidden_states)
+ hidden_states = hidden_gelu * hidden_linear
+ hidden_states = self.dropout(hidden_states)
+ hidden_states = self.wo(hidden_states)
+ return hidden_states
+
+
+import torch
+
+
+def forward(self, hidden_states):
+ if torch.is_autocast_enabled():
+ with torch.cuda.amp.autocast(enabled=False):
+ return self._forward(hidden_states)
+ else:
+ return self._forward(hidden_states)
+```
+
+자동 감지기는 전체 프레임의 입력과 출력에 대해서만 보고하므로, 어디를 살펴봐야 하는지 알면 특정 `forward` 함수의 중간 단계도 분석할 수 있습니다. 이 경우에는 `detect_overflow` 도우미 함수를 사용하여 원하는 위치에 감지기를 삽입할 수 있습니다. 예를 들어:
+
+```python
+from debug_utils import detect_overflow
+
+
+class T5LayerFF(nn.Module):
+ [...]
+
+ def forward(self, hidden_states):
+ forwarded_states = self.layer_norm(hidden_states)
+ detect_overflow(forwarded_states, "after layer_norm")
+ forwarded_states = self.DenseReluDense(forwarded_states)
+ detect_overflow(forwarded_states, "after DenseReluDense")
+ return hidden_states + self.dropout(forwarded_states)
+```
+
+여기서는 이를 추가하여 2개의 것을 추적하고 이제 `forwarded_states`의 `inf` 또는 `nan`이 중간에 감지되었는지를 추적합니다.
+
+실제로 위의 예제에서 각 호출이 `nn.Module`이기 때문에 탐지기가 이미 이를 보고합니다. 로컬에서 직접 계산하는 경우 이렇게 수행한다고 가정해 봅시다.
+
+또한, 자체 코드에서 디버거를 인스턴스화하는 경우 기본값에서 출력되는 프레임 수를 조정할 수 있습니다. 예를 들어:
+
+```python
+from transformers.debug_utils import DebugUnderflowOverflow
+
+debug_overflow = DebugUnderflowOverflow(model, max_frames_to_save=100)
+```
+
+### 특정 배치의 절댓값 최소 및 최대 값 추적 [[specific-batch-absolute-min-and-max-value-tracing]]
+
+동일한 디버깅 클래스는 언더플로우/오버플로우 감지 기능이 꺼진 상태에서 배치별 추적에도 사용할 수 있습니다.
+
+예를 들어, 특정 배치의 각 `forward` 호출의 모든 구성 성분에 대한 절대 최솟값과 최댓값을 확인하고, 이를 배치 1과 3에 대해서만 수행하려면 다음과 같이 이 클래스를 인스턴스화합니다:
+
+```python
+debug_overflow = DebugUnderflowOverflow(model, trace_batch_nums=[1, 3])
+```
+
+그러면 이제 배치 1과 3 전체가 언더플로우/오버플로우 감지기와 동일한 형식으로 추적됩니다.
+
+배치는 0부터 시작합니다.
+
+이는 프로그램이 특정 배치 번호 이후에 오작동하기 시작하는 것을 알고 있는 경우에 유용합니다. 그렇기 때문에 해당 영역으로 바로 이동할 수 있습니다. 이런 구성에 대한 샘플 축소된 출력은 다음과 같습니다.
+
+```
+ *** Starting batch number=1 ***
+abs min abs max metadata
+ shared Embedding
+1.01e-06 7.92e+02 weight
+0.00e+00 2.47e+04 input[0]
+5.36e-05 7.92e+02 output
+[...]
+ decoder.dropout Dropout
+1.60e-07 2.27e+01 input[0]
+0.00e+00 2.52e+01 output
+ decoder T5Stack
+ not a tensor output
+ lm_head Linear
+1.01e-06 7.92e+02 weight
+0.00e+00 1.11e+00 input[0]
+6.06e-02 8.39e+01 output
+ T5ForConditionalGeneration
+ not a tensor output
+
+ *** Starting batch number=3 ***
+abs min abs max metadata
+ shared Embedding
+1.01e-06 7.92e+02 weight
+0.00e+00 2.78e+04 input[0]
+5.36e-05 7.92e+02 output
+[...]
+```
+
+여기에서는 모델의 forward 호출 수와 동일한 수의 프레임이 덤프되므로 많은 수의 프레임이 생성됩니다. 따라서 원하는 것일 수도 있고 아닐 수도 있습니다. 그러나 때로는 일반 디버거보다 디버깅 목적으로 더 쉽게 사용할 수 있습니다. 예를 들어, 문제가 배치 번호 150에서 시작하는 경우 149와 150의 추적을 덤프하고 숫자가 어디서부터 다르게 되었는지 비교할 수 있습니다.
+
+또한, 훈련을 중지할 배치 번호를 지정할 수도 있습니다. 다음과 같이 지정할 수 있습니다.
+
+```python
+debug_overflow = DebugUnderflowOverflow(model, trace_batch_nums=[1, 3], abort_after_batch_num=3)
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/deepspeed.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/deepspeed.md
new file mode 100644
index 0000000000000000000000000000000000000000..48758ad9d52e2ddc6d7ed8e29c1fe580bed9cd70
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/deepspeed.md
@@ -0,0 +1,1220 @@
+
+
+# DeepSpeed[[deepspeed]]
+
+[DeepSpeed](https://www.deepspeed.ai/)는 분산 학습 메모리를 효율적이고 빠르게 만드는 PyTorch 최적화 라이브러리입니다. 그 핵심은 대규모 모델을 규모에 맞게 훈련할 수 있는 [Zero Redundancy Optimizer(ZeRO)](https://hf.co/papers/1910.02054)입니다. ZeRO는 여러 단계로 작동합니다:
+
+* ZeRO-1, GPU 간 최적화 상태 분할
+* ZeRO-2, GPU 간 그레이디언트 분할
+* ZeRO-3, GPU 간 매개변수 분할
+
+GPU가 제한된 환경에서 ZeRO는 최적화 메모리와 계산을 GPU에서 CPU로 오프로드하여 단일 GPU에 대규모 모델을 장착하고 훈련할 수 있습니다. DeepSpeed는 모든 ZeRO 단계 및 오프로딩을 위해 Transformers [`Trainer`] 클래스와 통합되어 있습니다. 구성 파일을 제공하거나 제공된 템플릿을 사용하기만 하면 됩니다. 추론의 경우, Transformers는 대용량 모델을 가져올 수 있으므로 ZeRO-3 및 오프로딩을 지원합니다.
+
+이 가이드에서는 DeepSpeed 트레이닝을 배포하는 방법, 활성화할 수 있는 기능, 다양한 ZeRO 단계에 대한 구성 파일 설정 방법, 오프로딩, 추론 및 [`Trainer`] 없이 DeepSpeed를 사용하는 방법을 안내해 드립니다.
+
+## 설치[[installation]]
+
+DeepSpeed는 PyPI 또는 Transformers에서 설치할 수 있습니다(자세한 설치 옵션은 DeepSpeed [설치 상세사항](https://www.deepspeed.ai/tutorials/advanced-install/) 또는 GitHub [README](https://github.com/deepspeedai/DeepSpeed#installation)를 참조하세요).
+
+
+
+DeepSpeed를 설치하는 데 문제가 있는 경우 [DeepSpeed CUDA 설치](../debugging#deepspeed-cuda-installation) 가이드를 확인하세요. DeepSpeed에는 pip 설치 가능한 PyPI 패키지로 설치할 수 있지만, 하드웨어에 가장 잘 맞고 PyPI 배포판에서는 제공되지 않는 1비트 Adam과 같은 특정 기능을 지원하려면 [소스에서 설치하기](https://www.deepspeed.ai/tutorials/advanced-install/#install-deepspeed-from-source)를 적극 권장합니다.
+
+
+
+
+
+
+```bash
+pip install deepspeed
+```
+
+
+
+
+```bash
+pip install transformers[deepspeed]
+```
+
+
+
+
+## 메모리 요구량[[memory-requirements]]
+
+시작하기 전에 모델에 맞는 충분한 GPU 및 CPU 메모리가 있는지 확인하는 것이 좋습니다. DeepSpeed는 필요한 CPU/GPU 메모리를 추정할 수 있는 도구를 제공합니다. 예를 들어, 단일 GPU에서 [bigscience/T0_3B](bigscience/T0_3B) 모델의 메모리 요구 사항을 추정할 수 있습니다:
+
+```bash
+$ python -c 'from transformers import AutoModel; \
+from deepspeed.runtime.zero.stage3 import estimate_zero3_model_states_mem_needs_all_live; \
+model = AutoModel.from_pretrained("bigscience/T0_3B"); \
+estimate_zero3_model_states_mem_needs_all_live(model, num_gpus_per_node=1, num_nodes=1)'
+[...]
+Estimated memory needed for params, optim states and gradients for a:
+HW: Setup with 1 node, 1 GPU per node.
+SW: Model with 2783M total params, 65M largest layer params.
+ per CPU | per GPU | Options
+ 70.00GB | 0.25GB | offload_param=cpu , offload_optimizer=cpu , zero_init=1
+ 70.00GB | 0.25GB | offload_param=cpu , offload_optimizer=cpu , zero_init=0
+ 62.23GB | 5.43GB | offload_param=none, offload_optimizer=cpu , zero_init=1
+ 62.23GB | 5.43GB | offload_param=none, offload_optimizer=cpu , zero_init=0
+ 0.37GB | 46.91GB | offload_param=none, offload_optimizer=none, zero_init=1
+ 15.56GB | 46.91GB | offload_param=none, offload_optimizer=none, zero_init=0
+```
+
+즉, CPU 오프로드가 없는 단일 80GB GPU 또는 오프로드 할 8GB GPU와 최대 60GB CPU가 필요합니다 (이는 매개변수, 최적화 상태 및 그레이디언트에 대한 메모리 요구 사항일 뿐이며 CUDA 커널 및 활성화에는 조금 더 필요합니다). 또한 더 작은 GPU를 대여하거나 구입하는 것이 더 저렴하지만 모델을 훈련하는 데 시간이 더 오래 걸리므로 비용과 속도 간의 균형을 고려해야 합니다.
+
+GPU 메모리가 충분하다면 CPU/NVMe 오프로드를 비활성화하여 모든 작업을 더 빠르게 처리하세요.
+
+## ZeRO 단계 설정하기[[select-a-zero-stage]]
+
+DeepSpeed를 설치하고 메모리 요구 사항을 더 잘 파악했다면 다음 단계는 사용할 ZeRO 스테이지를 선택하는 것입니다. 가장 빠르고 메모리 효율이 높은 순서대로 정렬하면 다음과 같습니다:
+
+| 속도 | 메모리 효율 |
+|------------------|------------------|
+| ZeRO-1 | ZeRO-3 + offload |
+| ZeRO-2 | ZeRO-3 |
+| ZeRO-2 + offload | ZeRO-2 + offload |
+| ZeRO-3 | ZeRO-2 |
+| ZeRO-3 + offload | ZeRO-1 |
+
+자신에게 가장 적합한 방법을 찾으려면 가장 빠른 방법부터 시작하고 메모리가 부족하면 더 느리지만 메모리 효율이 높은 다음 단계를 시도하세요. 속도와 메모리 사용량 사이의 적절한 균형을 찾기 위해 (가장 메모리 효율적이거나 가장 빠른 것부터 시작하여) 원하는 방향으로 자유롭게 작업하세요.
+
+일반적으로 사용할 수 있는 프로세스는 다음과 같습니다(배치 크기 1로 시작):
+
+1. 그레이디언트 체크포인팅 활성화
+2. ZeRO-2 시도
+3. ZeRO-2와 매개변수 오프로드 시도
+4. ZeRO-3 시도
+5. ZeRO-3과 매개변수 CPU 오프로드 시도
+6. ZeRO-3, 매개변수와 옵티마이저 CPU 오프로드 시도
+7. [`~GenerationMixin.generate`] 메소드를 사용하는 경우 더 좁은 빔 서치 검색 범위와 같은 다양한 기본값을 낮춰보기
+8. 전체 정밀도 가중치보다 반정밀도(구형 GPU 구조의 경우 fp16, 암페어 이후 GPU의 경우 bf16)를 혼합해보기
+9. 가능하면 하드웨어를 더 추가하거나 Infinity가 매개변수와 옵티마이저를 NVMe로 오프로드하도록 활성화
+10. 메모리가 부족하지 않으면 유효 처리량을 측정한 다음 배치 크기를 최대한 크게 늘려 GPU 효율성을 극대화
+11. 마지막으로 일부 오프로드 기능을 비활성화하거나 더 빠른 ZeRO 스테이지를 사용하고 배치 크기를 늘리거나 줄여 속도와 메모리 사용량 간의 최적의 균형을 찾아 트레이닝 설정을 최적화
+
+
+## DeepSpeed 구성 파일[[deepspeed-configuration-file]]
+
+DeepSpeed는 트레이닝 실행 방법을 구성하는 모든 매개변수가 포함된 구성 파일을 통해 [`Trainer`] 클래스와 함께 작동합니다. 트레이닝 스크립트를 실행하면 DeepSpeed는 [`Trainer`]로부터 받은 구성을 콘솔에 기록하므로 어떤 구성이 사용되었는지 정확히 확인할 수 있습니다.
+
+
+
+DeepSpeed 구성 옵션의 전체 목록은 [DeepSpeed Configuration JSON](https://www.deepspeed.ai/docs/config-json/)에서 확인할 수 있습니다. 또한 [DeepSpeedExamples](https://github.com/deepspeedai/DeepSpeedExamples) 리포지토리 또는 기본 [DeepSpeed](https://github.com/deepspeedai/DeepSpeed) 리포지토리에서 다양한 DeepSpeed 구성 예제에 대한 보다 실용적인 예제를 찾을 수 있습니다. 구체적인 예제를 빠르게 찾으려면 다음과 같이 하세요:
+
+```bash
+git clone https://github.com/deepspeedai/DeepSpeedExamples
+cd DeepSpeedExamples
+find . -name '*json'
+# Lamb 옵티마이저 샘플 찾기
+grep -i Lamb $(find . -name '*json')
+```
+
+
+
+명령줄 인터페이스에서 트레이닝하는 경우 DeepSpeed 구성 파일은 JSON 파일의 경로로 전달되거나 노트북 설정에서 [`Trainer`]를 사용하는 경우 중첩된 `dict` 객체로 전달됩니다.
+
+
+
+
+```py
+TrainingArguments(..., deepspeed="path/to/deepspeed_config.json")
+```
+
+
+
+
+```py
+ds_config_dict = dict(scheduler=scheduler_params, optimizer=optimizer_params)
+args = TrainingArguments(..., deepspeed=ds_config_dict)
+trainer = Trainer(model, args, ...)
+```
+
+
+
+
+### DeepSpeed와 Trainer 매개변수[[deepspeed-and-trainer-parameters]]
+
+구성 매개변수에는 세 가지 유형이 있습니다:
+
+1. 일부 구성 매개변수는 [`Trainer`]와 DeepSpeed가 공유하며, 정의가 충돌하는 경우 오류를 식별하기 어려울 수 있습니다. 이러한 공유 구성 매개변수는 [`Trainer`] 명령줄 인수에서 쉽게 설정할 수 있습니다.
+
+2. 모델 설정에서 자동으로 도출되는 일부 설정 매개변수는 수동으로 값을 조정할 필요가 없습니다. [`Trainer`]는 구성 값 `auto`를 사용하여 가장 정확하거나 효율적인 값을 설정합니다. 직접 구성 매개변수를 명시적으로 설정할 수도 있지만, [`Trainer`] 인수와 DeepSpeed 설정 매개변수가 일치하도록 주의해야 합니다. 일치하지 않으면 감지하기 매우 어려운 방식으로 훈련이 실패할 수 있습니다!
+
+3. 교육 요구 사항에 따라 수동으로 설정해야 하는 일부 설정 매개변수는 DeepSpeed에만 해당됩니다.
+
+DeepSpeed 구성을 수정하고 [`TrainingArguments`]를 편집할 수도 있습니다:
+
+1. 기본 구성으로 사용할 DeepSpeed 구성 파일을 생성하거나 로드합니다.
+2. 다음 DeepSpeed 구성을 기반으로 [`TrainingArguments`] 객체를 생성합니다.
+
+`scheduler.params.total_num_steps`와 같은 일부 값은 트레이닝 중 [`Trainer`]에 의해 계산됩니다.
+
+### ZeRO 구성[[zero-configuration]]
+
+세 가지 구성이 있으며, 각 구성은 서로 다른 ZeRO 단계에 해당합니다. 1단계는 확장성 측면에서 그다지 눈여겨볼만하지 않으므로 이 가이드에서는 2단계와 3단계에 중점을 둡니다. `zero_optimization` 구성에는 활성화할 항목과 구성 방법에 대한 모든 옵션이 포함되어 있습니다. 각 매개변수에 대한 자세한 설명은 [DeepSpeed 구성 JSON](https://www.deepspeed.ai/docs/config-json/) 참조를 참조하세요.
+
+
+DeepSpeed는 매개변수 이름의 유효성을 검사하지 않으며 오타가 있으면 매개변수의 기본 설정으로 대체합니다. DeepSpeed 엔진 시작 로그 메시지를 보고 어떤 값을 사용할지 확인할 수 있습니다.
+
+
+
+[`Trainer`]는 동등한 명령줄 인수를 제공하지 않으므로 다음 구성은 DeepSpeed로 설정해야 합니다.
+
+
+
+
+ZeRO-1은 옵티마이저 상태를 GPU에 분할하여 약간의 속도 향상을 기대할 수 있습니다. ZeRO-1 구성은 다음과 같이 설정할 수 있습니다:
+
+```yml
+{
+ "zero_optimization": {
+ "stage": 1
+ }
+}
+```
+
+
+
+
+ZeRO-2는 GPU에서 옵티마이저와 그레이디언트를 분할합니다. 이 단계는 추론과 관련이 없는 기능이기 때문에 주로 훈련에 사용됩니다. 더 나은 성능을 위해 구성해야 할 몇 가지 중요한 매개변수는 다음과 같습니다:
+
+* GPU 메모리 사용량을 줄이려면 `offload_optimizer`를 활성화해야 합니다.
+* `true`로 설정된 경우 `overlap_comm`은 GPU 메모리 사용량 증가를 상쇄하여 지연 시간을 줄입니다. 이 기능은 4.5배의 `allgather_bucket_size` 및 `reduce_bucket_size`값을 사용합니다. 이 예에서는 `5e8`로 설정되어 있으므로 9GB의 GPU 메모리가 필요합니다. GPU 메모리가 8GB 이하인 경우, 메모리 요구량을 낮추고 메모리 부족(OOM) 오류를 방지하기 위해 `overlap_comm`을 줄여야 합니다.
+* `allgather_bucket_size`와 `reduce_bucket_size`는 사용 가능한 GPU 메모리와 통신 속도를 절충합니다. 값이 작을수록 통신 속도가 느려지고 더 많은 GPU 메모리를 사용할 수 있습니다. 예를 들어, 배치 크기가 큰 것이 약간 느린 훈련 시간보다 더 중요한지 균형을 맞출 수 있습니다.
+* DeepSpeed 0.4.4에서는 CPU 오프로딩을 위해 `round_robin_gradients`를 사용할 수 있습니다. 이 기능은 세분화된 그레이디언트 파티셔닝을 통해 등급 간 그레이디언트 복사를 CPU 메모리로 병렬화합니다. 성능 이점은 그레이디언트 누적 단계(최적화 단계 간 복사 횟수 증가) 또는 GPU 수(병렬 처리 증가)에 따라 증가합니다.
+
+```yml
+{
+ "zero_optimization": {
+ "stage": 2,
+ "offload_optimizer": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "allgather_partitions": true,
+ "allgather_bucket_size": 5e8,
+ "overlap_comm": true,
+ "reduce_scatter": true,
+ "reduce_bucket_size": 5e8,
+ "contiguous_gradients": true
+ "round_robin_gradients": true
+ }
+}
+```
+
+
+
+
+ZeRO-3는 옵티마이저, 그래디언트, 매개변수를 여러 GPU에 걸쳐 분할합니다. ZeRO-2와 달리 ZeRO-3는 여러 GPU에 대규모 모델을 가져올 수 있기 때문에 훈련 외에도 추론에도 사용할 수 있습니다. 구성해야 할 몇 가지 중요한 매개변수는 다음과 같습니다:
+
+* `device: "cpu"` 는 GPU 메모리가 부족하고 사용 가능한 CPU 메모리가 있는 경우 도움이 될 수 있습니다. 이를 통해 모델 매개변수를 CPU로 오프로드할 수 있습니다.
+* `pin_memory: true` 는 처리량을 향상시킬 수 있지만, 핀 메모리는 메모리를 요청한 특정 프로세스를 위해 예약되어 있고 일반적으로 일반 CPU 메모리보다 훨씬 빠르게 액세스되기 때문에 다른 프로세스에서 사용할 수 있는 메모리가 줄어듭니다.
+* `stage3_max_live_parameters` 는 특정 시간에 GPU에 유지하려는 전체 매개변수의 상한값입니다. OOM 오류가 발생하면 이 값을 줄이세요.
+* `stage3_max_reuse_distance` 는 향후 매개변수를 다시 사용할 시기를 결정하는 값으로, 매개변수를 버릴지 유지할지 결정하는 데 도움이 됩니다. 매개변수를 재사용할 경우(`stage3_max_reuse_distance`보다 작은 값인 경우) 통신 오버헤드를 줄이기 위해 매개변수를 유지합니다. 이 기능은 활성화 체크포인팅이 활성화되어 있고 역전파 계산시까지 순전파 시점의 매개변수를 유지하려는 경우에 매우 유용합니다. 그러나 OOM 오류가 발생하면 이 값을 줄이세요.
+* 모델 저장 시 `stage3_gather_16bit_weights_on_model_save`는 fp16 가중치를 통합합니다. 대규모 모델을 학습하거나 여러 GPU를 사용할 경우 메모리와 속도 측면에서 비용이 많이 듭니다. 훈련을 재개할 계획이라면 이 옵션을 활성화해야 합니다.
+* `sub_group_size` 는 최적화 단계에서 업데이트되는 매개변수를 제어합니다. 매개변수는 `sub_group_size`의 버킷으로 그룹화되며 각 버킷은 한 번에 하나씩 업데이트됩니다. NVMe 오프로드와 함께 사용하는 경우 `sub_group_size`는 최적화 단계 중 모델 상태가 CPU 메모리로 이동하는 시점을 결정합니다. 이렇게 하면 매우 큰 모델의 CPU 메모리 부족을 방지할 수 있습니다. NVMe 오프로드를 사용하지 않는 경우 `sub_group_size`를 기본값으로 둘 수 있지만, 사용하는 경우 변경하는 것이 좋습니다:
+
+ 1. 옵티마이저 단계에서 OOM 오류가 발생합니다. 이 경우, 임시 버퍼의 메모리 사용량을 줄이려면 `sub_group_size`를 줄이세요.
+ 2. 옵티마이저 단계에서 시간이 너무 오래 걸립니다. 이 경우 데이터 버퍼 증가로 인한 대역폭 사용률을 개선하기 위해 `sub_group_size`를 늘리세요.
+
+* `reduce_bucket_size`, `stage3_prefetch_bucket_size`, `stage3_param_persistence_threshold`는 모델의 숨겨진 크기에 따라 달라집니다. 이 값들을 `auto`으로 설정하고 [`Trainer`]가 자동으로 값을 할당하도록 허용하는 것이 좋습니다.
+
+```yml
+{
+ "zero_optimization": {
+ "stage": 3,
+ "offload_optimizer": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "offload_param": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "overlap_comm": true,
+ "contiguous_gradients": true,
+ "sub_group_size": 1e9,
+ "reduce_bucket_size": "auto",
+ "stage3_prefetch_bucket_size": "auto",
+ "stage3_param_persistence_threshold": "auto",
+ "stage3_max_live_parameters": 1e9,
+ "stage3_max_reuse_distance": 1e9,
+ "stage3_gather_16bit_weights_on_model_save": true
+ }
+}
+```
+
+[`deepspeed.zero.Init`](https://deepspeed.readthedocs.io/en/latest/zero3.html#deepspeed.zero.Init) 컨텍스트 매니저를 사용하면 모델을 더 빠르게 초기화할 수 있습니다:
+
+```py
+from transformers import T5ForConditionalGeneration, T5Config
+import deepspeed
+
+with deepspeed.zero.Init():
+ config = T5Config.from_pretrained("google-t5/t5-small")
+ model = T5ForConditionalGeneration(config)
+```
+
+사전 학습된 모델의 경우, 딥스피드 구성 파일에 `is_deepspeed_zero3_enabled: true`가 [`TrainingArguments`]에 설정되어 있어야 하며, ZeRO 구성이 활성화되어 있어야 합니다. 훈련된 모델 [`~PreTrainedModel.from_pretrained`]을 호출하기 **전에** [`TrainingArguments`] 객체를 생성해야 합니다.
+
+```py
+from transformers import AutoModel, Trainer, TrainingArguments
+
+training_args = TrainingArguments(..., deepspeed=ds_config)
+model = AutoModel.from_pretrained("google-t5/t5-small")
+trainer = Trainer(model=model, args=training_args, ...)
+```
+
+fp16 가중치가 단일 GPU에 맞지 않는 경우 ZeRO-3이 필요합니다. fp16 가중치를 로드할 수 있는 경우, [`~PreTrainedModel.from_pretrained`]에 `torch_dtype=torch.float16`을 지정해야 합니다.
+
+ZeRO-3의 또 다른 고려 사항은 여러 개의 GPU를 사용하는 경우 현재 실행 중인 레이어의 매개변수가 아닌 한 단일 GPU에 모든 매개변수가 없다는 것입니다. 사전 훈련된 모델 가중치를 [`~PreTrainedModel.from_pretrained`]에 로드하는 등 모든 레이어의 모든 매개변수에 한 번에 액세스하려면 한 번에 하나의 레이어를 로드하고 즉시 모든 GPU에 파티셔닝합니다. 이는 매우 큰 모델의 경우 메모리 제한으로 인해 하나의 GPU에 가중치를 로드한 다음 다른 GPU에 분산할 수 없기 때문입니다.
+
+다음과 같이 보이는 모델 매개변수 가중치(여기서 `tensor([1.])`) 또는 매개변수 크기가 더 큰 다차원 형태 대신 1인 경우, 이는 매개변수가 분할되어 있으며 이것이 ZeRO-3 플레이스홀더인 것을 의미합니다.
+
+```py
+tensor([1.0], device="cuda:0", dtype=torch.float16, requires_grad=True)
+```
+
+
+
+ZeRO-3로 대규모 모델을 초기화하고 매개변수에 액세스하는 방법에 대한 자세한 내용은 [Constructing Massive Models](https://deepspeed.readthedocs.io/en/latest/zero3.html#constructing-massive-models) 및 [Gathering Parameters](https://deepspeed.readthedocs.io/en/latest/zero3.html#gathering-parameters) 가이드를 참조하세요.
+
+
+
+
+
+
+### NVMe 설정[[nvme-configuration]]
+
+[ZeRO-Infinity](https://hf.co/papers/2104.07857)를 사용하면 모델 상태를 CPU 및/또는 NVMe로 오프로드하여 더 많은 메모리를 절약할 수 있습니다. 스마트 파티셔닝 및 타일링 알고리즘을 통해 각 GPU는 오프로딩 중에 매우 적은 양의 데이터를 주고받을 수 있으므로 최신 NVMe는 훈련 프로세스에 사용할 수 있는 것보다 훨씬 더 큰 총 메모리 풀에 맞출 수 있습니다. ZeRO-Infinity에는 ZeRO-3가 필요합니다.
+
+사용 가능한 CPU 및/또는 NVMe 메모리에 따라 [옵티마이저](https://www.deepspeed.ai/docs/config-json/#optimizer-offloading)와 [매개변수](https://www.deepspeed.ai/docs/config-json/#parameter-offloading) 중 하나만 오프로드하거나 아무것도 오프로드하지 않을 수 있습니다. 또한 일반 하드 드라이브나 솔리드 스테이트 드라이브에서도 작동하지만 속도가 현저히 느려지므로 `nvme_path`가 NVMe 장치를 가리키고 있는지 확인해야 합니다. 최신 NVMe를 사용하면 읽기 작업의 경우 최대 3.5GB/s, 쓰기 작업의 경우 최대 3GB/s의 전송 속도를 기대할 수 있습니다. 마지막으로, 트레이닝 설정에서 [벤치마크 실행하기](https://github.com/deepspeedai/DeepSpeed/issues/998)을 통해 최적의 'aio' 구성을 결정합니다.
+
+아래 예제 ZeRO-3/Infinity 구성 파일은 대부분의 매개변수 값을 `auto`으로 설정하고 있지만, 수동으로 값을 추가할 수도 있습니다.
+
+```yml
+{
+ "fp16": {
+ "enabled": "auto",
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ },
+
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "betas": "auto",
+ "eps": "auto",
+ "weight_decay": "auto"
+ }
+ },
+
+ "scheduler": {
+ "type": "WarmupLR",
+ "params": {
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto"
+ }
+ },
+
+ "zero_optimization": {
+ "stage": 3,
+ "offload_optimizer": {
+ "device": "nvme",
+ "nvme_path": "/local_nvme",
+ "pin_memory": true,
+ "buffer_count": 4,
+ "fast_init": false
+ },
+ "offload_param": {
+ "device": "nvme",
+ "nvme_path": "/local_nvme",
+ "pin_memory": true,
+ "buffer_count": 5,
+ "buffer_size": 1e8,
+ "max_in_cpu": 1e9
+ },
+ "aio": {
+ "block_size": 262144,
+ "queue_depth": 32,
+ "thread_count": 1,
+ "single_submit": false,
+ "overlap_events": true
+ },
+ "overlap_comm": true,
+ "contiguous_gradients": true,
+ "sub_group_size": 1e9,
+ "reduce_bucket_size": "auto",
+ "stage3_prefetch_bucket_size": "auto",
+ "stage3_param_persistence_threshold": "auto",
+ "stage3_max_live_parameters": 1e9,
+ "stage3_max_reuse_distance": 1e9,
+ "stage3_gather_16bit_weights_on_model_save": true
+ },
+
+ "gradient_accumulation_steps": "auto",
+ "gradient_clipping": "auto",
+ "steps_per_print": 2000,
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "wall_clock_breakdown": false
+}
+```
+
+## DeepSpeed 구성[[deepspeed-features]]
+
+이 섹션에서 간략하게 설명하는 몇 가지 중요한 매개변수를 DeepSpeed 구성 파일에 지정할 수 있습니다.
+
+### 활성화/그레이디언트 체크포인팅[[activationgradient-checkpointing]]
+
+활성화 및 그레이디언트 체크포인팅은 속도를 더 많은 GPU 메모리와 교환하여 GPU 메모리가 부족한 상황을 극복하거나 배치 크기를 늘려 성능을 향상시킬 수 있습니다. 이 기능을 활성화하려면 다음과 같이 하세요:
+
+1. 허깅 페이스 모델의 경우, [`Trainer`]에서 `model.gradient_checkpointing_enable()` 또는 `--gradient_checkpointing`을 설정합니다.
+2. 허깅 페이스가 아닌 모델의 경우, 딥스피드 [Activation Checkpointing API](https://deepspeed.readthedocs.io/en/latest/activation-checkpointing.html)를 사용합니다. 트랜스포머 모델링 코드를 대체하고 `torch.utils.checkpoint`를 DeepSpeed API로 대체할 수도 있습니다. 이 접근 방식은 순방향 활성화를 다시 계산하는 대신 CPU 메모리로 오프로드할 수 있으므로 더 유연합니다.
+
+### 옵티마이저와 스케줄러[[optimizer-and-scheduler]]
+
+`offload_optimizer`를 활성화하지 않는 한 DeepSpeed와 트랜스포머 옵티마이저 및 스케줄러를 혼합하여 사용할 수 있습니다. `offload_optimizer`를 활성화하면 CPU와 GPU 구현이 모두 있는 경우 DeepSpeed가 아닌 최적화기(LAMB 제외)를 사용할 수 있습니다.
+
+
+
+구성 파일의 최적화 프로그램 및 스케줄러 매개변수는 명령줄에서 설정할 수 있으므로 오류를 찾기 어렵지 않습니다. 예를 들어 학습 속도가 다른 곳에서 다른 값으로 설정된 경우 명령줄에서 이를 재정의할 수 있습니다. 최적화 프로그램 및 스케줄러 매개변수 외에도 [`Trainer`] 명령줄 인수가 DeepSpeed 구성과 일치하는지 확인해야 합니다.
+
+
+
+
+
+
+DeepSpeed는 여러 [옵티마이저](https://www.deepspeed.ai/docs/config-json/#optimizer-parameters)를 제공하지만(Adam, AdamW, OneBitAdam 및 LAMB) PyTorch에서 다른 옵티마이저를 가져올 수도 있습니다. 설정에서 옵티마이저를 구성하지 않으면 [`Trainer`]가 자동으로 AdamW를 선택하고 명령줄에서 제공된 값 또는 기본값을 사용합니다: `lr`, `adam_beta1`, `adam_beta2`, `adam_epsilon`, `weight_decay`.
+
+매개변수를 `"auto"`으로 설정하거나 원하는 값을 직접 수동으로 입력할 수 있습니다.
+
+```yaml
+{
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "betas": "auto",
+ "eps": "auto",
+ "weight_decay": "auto"
+ }
+ }
+}
+```
+
+최상위 구성에 다음을 추가하여 지원되지 않는 옵티마이저를 사용할 수도 있습니다.
+
+```yaml
+{
+ "zero_allow_untested_optimizer": true
+}
+```
+
+DeepSpeed==0.8.3부터 오프로드를 사용하려면 오프로드가 DeepSpeed의 CPU Adam 옵티마이저에서 가장 잘 작동하므로 최상위 수준 구성에 다음 사항을 추가해야 합니다.
+
+```yaml
+{
+ "zero_force_ds_cpu_optimizer": false
+}
+```
+
+
+
+
+DeepSpeed는 LRRangeTest, OneCycle, WarmupLR 및 WarmupDecayLR learning rate[schedulers](https://www.deepspeed.ai/docs/config-json/#scheduler-parameters)를 지원합니다.
+
+트랜스포머와 DeepSpeed는 동일한 두 가지 스케줄러를 제공합니다:
+
+* WarmupLR은 Transformers의 `--lr_scheduler_type constant_warmup`과 동일합니다.
+* WarmupDecayLR은 Transformers의 `--lr_scheduler_type linear`와 동일합니다(Transformers에서 사용되는 기본 스케줄러입니다).
+
+설정에서 스케줄러를 구성하지 않으면[`Trainer`]는 자동으로 WarmupDecayLR을 선택하고 명령줄에서 제공된 값 또는 기본값을 사용합니다: `warmup_min_lr`, `warmup_max_lr`, `warmup_num_steps`, `total_num_steps` (`max_steps`가 제공되지 않으면 런타임 중에 자동으로 계산됨).
+
+매개변수를 `"auto"`으로 설정하거나 원하는 값을 직접 수동으로 입력할 수 있습니다.
+
+```yaml
+{
+ "scheduler": {
+ "type": "WarmupDecayLR",
+ "params": {
+ "total_num_steps": "auto",
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto"
+ }
+ }
+}
+```
+
+
+
+
+### 정밀도[[precision]]
+
+DeepSpeed는 fp32, fp16 및 bf16 혼합 정밀도를 지원합니다.
+
+
+
+
+모델이 혼합 정밀도로 사전 학습되지 않은 경우와 같이 혼합 정밀도로 잘 작동하지 않는 경우 NaN 손실을 유발할 수 있는 오버플로 또는 언더플로 문제가 발생할 수 있습니다. 이러한 경우에는 기본 fp16 모드를 명시적으로 비활성화하여 전체 fp32 정밀도를 사용해야 합니다.
+
+```yaml
+{
+ "fp16": {
+ "enabled": false
+ }
+}
+```
+
+Ampere GPU 및 PyTorch 1.7 이상의 경우 일부 연산에 대해 더 효율적인 [tf32](https://pytorch.org/docs/stable/notes/cuda.html#tensorfloat-32-tf32-on-ampere-devices) 형식으로 자동 전환되지만 결과는 여전히 fp32로 표시됩니다. [`Trainer`]에서 `--tf32`를 설정하여 활성화하고 `--tf32 0` 또는 `--no_tf32`를 비활성화하면 제어할 수 있습니다.
+
+
+
+
+PyTorch AMP와 같은 fp16 혼합 정밀도를 구성하면 메모리 사용량이 줄어들고 훈련 속도가 빨라집니다.[`Trainer`]는 `args.fp16_backend` 값에 따라 fp16을 자동으로 활성화 또는 비활성화하며, 나머지 구성은 사용자가 설정할 수 있습니다. 명령줄에서 다음 인수를 전달하면 fp16이 활성화됩니다: `fp16`, `--fp16_backend amp` 또는 `--fp16_full_eval`.
+
+```yaml
+{
+ "fp16": {
+ "enabled": "auto",
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ }
+}
+```
+
+추가 딥스피드 fp16 훈련 옵션은 [fp16 훈련 옵션](https://www.deepspeed.ai/docs/config-json/#fp16-training-options) 참조를 참조하세요.
+
+Apex와 같은 fp16 혼합 정밀도를 구성하려면 아래 그림과 같이 `"auto"` 또는 직접 값을 설정합니다.[`Trainer`]는 `args.fp16_backend` 및 `args.fp16_opt_level`의 값에 따라 `amp`를 자동으로 구성합니다. 다음 인수를 전달하면 명령줄에서 활성화할 수도 있습니다: `fp16`, `--fp16_backend apex` 또는 `--fp16_opt_level 01`.
+
+```yaml
+{
+ "amp": {
+ "enabled": "auto",
+ "opt_level": "auto"
+ }
+}
+```
+
+
+
+
+bf16을 사용하려면 DeepSpeed==0.6.0 이상이 필요합니다. bf16은 fp32와 동적 범위가 동일하며 손실 스케일링이 필요하지 않습니다. 그러나 [gradient accumulation](#gradient-accumulation)을 bf16과 함께 사용하면 이 형식의 낮은 정밀도로 인해 손실이 발생할 수 있으므로 원하지 않는 그레이디언트가 bf16에 누적될 수 있습니다.
+
+bf16은 설정 파일에서 설정하거나 다음 인수를 전달하면 명령줄에서 활성화할 수 있습니다: `--bf16` 또는 `--bf16_full_eval`.
+
+```yaml
+{
+ "bf16": {
+ "enabled": "auto"
+ }
+}
+```
+
+
+
+
+### 배치 크기[[batch-size]]
+
+배치 크기는 자동으로 구성하거나 명시적으로 설정할 수 있습니다. `"auto"` 옵션을 사용하도록 선택하면 [`Trainer`]는 `train_micro_batch_size_per_gpu`를 args.`per_device_train_batch_size`의 값으로, `train_batch_size`를 `args.world_size * args.per_device_train_batch_size * args.gradient_accumulation_steps`로 설정합니다.
+
+```yaml
+{
+ "train_micro_batch_size_per_gpu": "auto",
+ "train_batch_size": "auto"
+}
+```
+
+### 그레이디언트 누적[[gradient-accumulation]]
+
+그레이디언트 누적을 자동으로 구성하거나 명시적으로 설정할 수 있습니다. `"auto"` 옵션을 사용하도록 선택하면 [`Trainer`]가 `args.gradient_accumulation_steps`의 값으로 설정합니다.
+
+```yaml
+{
+ "gradient_accumulation_steps": "auto"
+}
+
+```
+
+### 그레이디언트 클리핑[[gradient-clipping]]
+
+그레이디언트 클리핑은 자동으로 구성하거나 명시적으로 설정할 수 있습니다. `"auto"` 옵션을 사용하도록 선택하면 [`Trainer`]가 `args.max_grad_norm`의 값으로 설정합니다.
+
+```yaml
+{
+ "gradient_clipping": "auto"
+}
+```
+
+### 통신 데이터 유형(Communication data type)[[communication-data-type]]
+
+축소, 수집 및 분산 작업과 같은 통신 집합체의 경우 별도의 데이터 유형이 사용됩니다.
+
+모든 수집 및 분산 작업은 데이터와 동일한 데이터 유형으로 수행됩니다. 예를 들어 bf16으로 훈련하는 경우, 수집은 비손실 연산이므로 데이터도 bf16으로 수집됩니다.
+
+예를 들어 그레이디언트가 여러 GPU에 걸쳐 평균화되는 경우와 같이 감소 연산은 손실이 발생합니다. 통신이 fp16 또는 bf16으로 수행되는 경우, 낮은 정밀도로 여러 숫자를 더하면 정확하지 않기 때문에 손실이 발생할 가능성이 더 높습니다. 특히 fp16보다 정밀도가 낮은 bf16의 경우 더욱 그렇습니다. 이러한 이유로 기울기를 평균화할 때 손실이 최소화되므로 감소 연산에는 fp16이 기본값으로 사용됩니다.
+
+통신 데이터 유형은 설정 파일에서 `communication_data_type` 매개변수를 설정하여 선택할 수 있습니다. 예를 들어, fp32를 선택하면 약간의 오버헤드가 추가되지만 감소 연산이 fp32에 누적되고 준비가 되면 훈련 중인 반정밀 dtype으로 다운캐스트됩니다.
+
+```yaml
+{
+ "communication_data_type": "fp32"
+}
+```
+
+## 모델 배포[[deployment]]
+
+[torchrun](https://pytorch.org/docs/stable/elastic/run.html), `deepspeed` 런처 또는 [Accelerate](https://huggingface.co/docs/accelerate/basic_tutorials/launch#using-accelerate-launch) 등 다양한 런처를 통해 DeepSpeed를 배포할 수 있습니다. 배포하려면 [`Trainer`] 명령줄에 `--deepspeed ds_config.json`을 추가합니다. 필요한 명령줄 인수를 코드에 추가하려면 DeepSpeed의 [`add_config_arguments`](https://deepspeed.readthedocs.io/en/latest/initialize.html#argument-parsing) 유틸리티를 사용하는 것이 좋습니다.
+
+이 가이드에서는 다양한 트레이닝 설정에 대해 `deepspeed` 런처로 DeepSpeed를 배포하는 방법을 보여드립니다. 보다 실용적인 사용 예제는 이 [post](https://github.com/huggingface/transformers/issues/8771#issuecomment-759248400)에서 확인할 수 있습니다.
+
+
+
+
+여러 GPU에 DeepSpeed를 배포하려면 `--num_gpus` 매개변수를 추가하세요. 사용 가능한 모든 GPU를 사용하려는 경우 `--num_gpus`를 추가할 필요가 없습니다. 아래 예제에서는 2개의 GPU를 사용합니다.
+
+```bash
+deepspeed --num_gpus=2 examples/pytorch/translation/run_translation.py \
+--deepspeed tests/deepspeed/ds_config_zero3.json \
+--model_name_or_path google-t5/t5-small --per_device_train_batch_size 1 \
+--output_dir output_dir --overwrite_output_dir --fp16 \
+--do_train --max_train_samples 500 --num_train_epochs 1 \
+--dataset_name wmt16 --dataset_config "ro-en" \
+--source_lang en --target_lang ro
+```
+
+
+
+
+단일 GPU에 DeepSpeed를 배포하려면 `--num_gpus` 매개변수를 추가하세요. GPU가 1개만 있는 경우 이 값을 명시적으로 설정할 필요는 없습니다. DeepSpeed는 지정된 노드에서 볼 수 있는 모든 GPU를 배포하므로 이 값을 명시적으로 설정할 필요는 없습니다.
+
+```bash
+deepspeed --num_gpus=1 examples/pytorch/translation/run_translation.py \
+--deepspeed tests/deepspeed/ds_config_zero2.json \
+--model_name_or_path google-t5/t5-small --per_device_train_batch_size 1 \
+--output_dir output_dir --overwrite_output_dir --fp16 \
+--do_train --max_train_samples 500 --num_train_epochs 1 \
+--dataset_name wmt16 --dataset_config "ro-en" \
+--source_lang en --target_lang ro
+```
+
+DeepSpeed는 단 하나의 GPU로도 여전히 유용합니다:
+
+1. 일부 계산과 메모리를 CPU로 오프로드하여 더 큰 배치 크기를 사용하거나 일반적으로 맞지 않는 매우 큰 모델을 맞추기 위해 모델에 더 많은 GPU 리소스를 사용할 수 있도록 합니다.
+2. 스마트 GPU 메모리 관리 시스템으로 메모리 조각화를 최소화하여 더 큰 모델과 데이터 배치에 맞출 수 있습니다.
+
+
+
+단일 GPU에서 더 나은 성능을 얻으려면 [ZeRO-2](#zero-configuration) 구성 파일에서 `allgather_bucket_size` 및 `reduce_bucket_size` 값을 2e8로 설정하세요.
+
+
+
+
+
+
+### 다중 노드 환경에서의 모델 배포[[multi-node-deployment]]
+
+노드는 워크로드를 실행하기 위한 하나 이상의 GPU입니다. 더 강력한 설정은 멀티 노드 설정으로, `deepspeed` 런처로 실행할 수 있습니다. 이 가이드에서는 각각 8개의 GPU가 있는 두 개의 노드가 있다고 가정해 보겠습니다. 첫 번째 노드는 `ssh hostname1`로, 두 번째 노드는 `ssh hostname2`로 접속할 수 있습니다. 두 노드 모두 비밀번호 없이 ssh를 통해 로컬로 서로 통신할 수 있어야 합니다.
+
+기본적으로 DeepSpeed는 멀티노드 환경에서 공유 저장소를 사용할 것으로 예상합니다. 그렇지 않고 각 노드가 로컬 파일 시스템만 볼 수 있는 경우, 공유 파일 시스템에 대한 액세스 없이 로딩할 수 있도록 [`checkpoint`](https://www.deepspeed.ai/docs/config-json/#checkpoint-options)를 포함하도록 구성 파일을 조정해야 합니다:
+
+```yaml
+{
+ "checkpoint": {
+ "use_node_local_storage": true
+ }
+}
+```
+
+[`Trainer`]의 ``--save_on_each_node` 인수를 사용하여 위의 `checkpoint`를 구성에 자동으로 추가할 수도 있습니다.
+
+
+
+
+[torchrun](https://pytorch.org/docs/stable/elastic/run.html)의 경우, 각 노드에 ssh로 접속한 후 두 노드 모두에서 다음 명령을 실행해야 합니다. 런처는 두 노드가 동기화될 때까지 기다렸다가 트레이닝을 시작합니다.
+
+```bash
+torchrun --nproc_per_node=8 --nnode=2 --node_rank=0 --master_addr=hostname1 \
+--master_port=9901 your_program.py --deepspeed ds_config.json
+```
+
+
+
+
+`deepspeed` 런처의 경우, 먼저 `hostfile`을 생성합니다.
+
+```bash
+hostname1 slots=8
+hostname2 slots=8
+```
+
+그런 다음 다음 명령어로 트레이닝을 시작할 수 있습니다. `deepspeed` 런처는 두 노드에서 동시에 명령을 자동으로 실행합니다.
+
+```bash
+deepspeed --num_gpus 8 --num_nodes 2 --hostfile hostfile --master_addr hostname1 --master_port=9901 \
+your_program.py --deepspeed ds_config.json
+```
+
+다중 노드 컴퓨팅 리소스 구성에 대한 자세한 내용은 [Resource Configuration (multi-node)](https://www.deepspeed.ai/getting-started/#resource-configuration-multi-node) 가이드를 참조하세요.
+
+
+
+
+### SLURM[[slurm]]
+
+SLURM 환경에서는 특정 SLURM 환경에 맞게 SLURM 스크립트를 조정해야 합니다.SLURM 스크립트 예시는 다음과 같습니다:
+
+```bash
+#SBATCH --job-name=test-nodes # 작업 이름
+#SBATCH --nodes=2 # 노드 수
+#SBATCH --ntasks-per-node=1 # 중요 - 노드당 분산 작업 1개!
+#SBATCH --cpus-per-task=10 # 작업당 CPU 코어 수
+#SBATCH --gres=gpu:8 # gpu 수
+#SBATCH --time 20:00:00 # 최대 실행 시간 (HH:MM:SS)
+#SBATCH --output=%x-%j.out # 출력 파일 이름
+
+export GPUS_PER_NODE=8
+export MASTER_ADDR=$(scontrol show hostnames $SLURM_JOB_NODELIST | head -n 1)
+export MASTER_PORT=9901
+
+srun --jobid $SLURM_JOBID bash -c 'python -m torch.distributed.run \
+ --nproc_per_node $GPUS_PER_NODE --nnodes $SLURM_NNODES --node_rank $SLURM_PROCID \
+ --master_addr $MASTER_ADDR --master_port $MASTER_PORT \
+your_program.py --deepspeed ds_config.json'
+```
+
+그런 다음 모든 노드에서 동시에 학습을 시작하는 다음 명령을 사용하여 다중 노드 배포를 예약할 수 있습니다.
+
+```bash
+sbatch launch.slurm
+```
+
+### 노트북[[notebook]]
+
+`deepspeed` 런처는 노트북에서의 배포를 지원하지 않으므로 분산 환경을 에뮬레이션해야 합니다. 하지만 이는 1개의 GPU에서만 작동합니다. 1개 이상의 GPU를 사용하려면 딥스피드가 작동할 수 있는 다중 프로세스 환경을 사용해야 합니다. 즉, 여기에 표시된 것처럼 에뮬레이션할 수 없는 `deepspeed` 런처를 사용해야 합니다.
+
+```py
+# DeepSpeed는 단일 프로세스만 사용하더라도 분산 환경을 필요로 합니다.
+# 이 코드로 분산 환경을 모방합니다.
+import os
+
+os.environ["MASTER_ADDR"] = "localhost"
+os.environ["MASTER_PORT"] = "9994" # RuntimeError: Address already in use 오류 발생 시 수정
+os.environ["RANK"] = "0"
+os.environ["LOCAL_RANK"] = "0"
+os.environ["WORLD_SIZE"] = "1"
+
+# 이제 평소와 같이 진행하되, DeepSpeed 설정 파일을 전달합니다.
+training_args = TrainingArguments(..., deepspeed="ds_config_zero3.json")
+trainer = Trainer(...)
+trainer.train()
+```
+
+현재 디렉터리의 노트북에 구성 파일을 즉석에서 만들고 싶다면 전용 셀을 만들 수 있습니다.
+
+```py
+%%bash
+cat <<'EOT' > ds_config_zero3.json
+{
+ "fp16": {
+ "enabled": "auto",
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ },
+
+ "optimizer": {
+ "type": "AdamW",
+ "params": {
+ "lr": "auto",
+ "betas": "auto",
+ "eps": "auto",
+ "weight_decay": "auto"
+ }
+ },
+
+ "scheduler": {
+ "type": "WarmupLR",
+ "params": {
+ "warmup_min_lr": "auto",
+ "warmup_max_lr": "auto",
+ "warmup_num_steps": "auto"
+ }
+ },
+
+ "zero_optimization": {
+ "stage": 3,
+ "offload_optimizer": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "offload_param": {
+ "device": "cpu",
+ "pin_memory": true
+ },
+ "overlap_comm": true,
+ "contiguous_gradients": true,
+ "sub_group_size": 1e9,
+ "reduce_bucket_size": "auto",
+ "stage3_prefetch_bucket_size": "auto",
+ "stage3_param_persistence_threshold": "auto",
+ "stage3_max_live_parameters": 1e9,
+ "stage3_max_reuse_distance": 1e9,
+ "stage3_gather_16bit_weights_on_model_save": true
+ },
+
+ "gradient_accumulation_steps": "auto",
+ "gradient_clipping": "auto",
+ "steps_per_print": 2000,
+ "train_batch_size": "auto",
+ "train_micro_batch_size_per_gpu": "auto",
+ "wall_clock_breakdown": false
+}
+EOT
+```
+
+트레이닝 스크립트가 노트북 셀이 아닌 파일에 있는 경우, 노트북 셀의 셸에서 `deepspeed`를 정상적으로 실행할 수 있습니다. 예를 들어 `run_translation.py`를 시작하려면 다음과 같이 하세요.:
+
+```py
+!git clone https://github.com/huggingface/transformers
+!cd transformers; deepspeed examples/pytorch/translation/run_translation.py ...
+```
+
+또한 `%%bash` 매직을 사용하여 여러 줄의 코드를 작성하여 셸 프로그램을 실행할 수도 있지만 교육이 완료될 때까지 로그를 볼 수 없습니다. `%%bash` 매직으로 분산 환경을 에뮬레이션할 필요는 없습니다.
+
+```py
+%%bash
+
+git clone https://github.com/huggingface/transformers
+cd transformers
+deepspeed examples/pytorch/translation/run_translation.py ...
+```
+
+## 모델 가중치 저장하기[[save-model-weights]]
+
+딥스피드는 기본 고정밀 fp32 가중치를 사용자 지정 체크포인트 최적화 파일(glob 패턴은 `global_step*/*optim_states.pt`처럼 보입니다)에 저장하고 일반 체크포인트 아래에 저장합니다.
+
+
+
+
+ZeRO-2로 훈련된 모델은 pytorch_model.bin 가중치를 fp16에 저장합니다. ZeRO-3으로 훈련된 모델의 모델 가중치를 fp16에 저장하려면 모델 가중치가 여러 GPU에 분할되어 있으므로 `“stage3_gather_16bit_weights_on_model_save”: true`를 설정해야 합니다. 그렇지 않으면 [`Trainer`]가 가중치를 fp16에 저장하지 않고 pytorch_model.bin 파일을 생성하지 않습니다. 이는 DeepSpeed의 state_dict에 실제 가중치 대신 플레이스홀더가 포함되어 있어 이를 로드할 수 없기 때문입니다.
+
+```yaml
+{
+ "zero_optimization": {
+ "stage3_gather_16bit_weights_on_model_save": true
+ }
+}
+```
+
+
+
+
+전체 정밀 가중치는 많은 메모리가 필요할 수 있으므로 트레이닝 중에 저장해서는 안 됩니다. 일반적으로 훈련이 완료된 후 오프라인으로 fp32 가중치를 저장하는 것이 가장 좋습니다. 그러나 여유 CPU 메모리가 많은 경우 훈련 중에 fp32 가중치를 저장할 수 있습니다. 이 섹션에서는 온라인과 오프라인 방식을 모두 다룹니다.
+
+### 온라인 환경[[online]]
+
+다음과 같이 최신 체크포인트를 로드하려면 체크포인트를 하나 이상 저장해야 합니다:
+
+```py
+from transformers.trainer_utils import get_last_checkpoint
+from deepspeed.utils.zero_to_fp32 import load_state_dict_from_zero_checkpoint
+
+checkpoint_dir = get_last_checkpoint(trainer.args.output_dir)
+fp32_model = load_state_dict_from_zero_checkpoint(trainer.model, checkpoint_dir)
+```
+
+`--load_best_model_at_end` 매개변수를 활성화하여 [`TrainingArguments`]에서 최적의 체크포인트를 추적하는 경우, 먼저 학습을 완료하고 최종 모델을 명시적으로 저장할 수 있습니다. 그런 다음 아래와 같이 다시 로드할 수 있습니다:
+
+```py
+from deepspeed.utils.zero_to_fp32 import load_state_dict_from_zero_checkpoint
+
+checkpoint_dir = os.path.join(trainer.args.output_dir, "checkpoint-final")
+trainer.deepspeed.save_checkpoint(checkpoint_dir)
+fp32_model = load_state_dict_from_zero_checkpoint(trainer.model, checkpoint_dir)
+```
+
+
+
+`load_state_dict_from_zero_checkpoint`가 실행되면 동일한 애플리케이션의 컨텍스트에서 모델을 더 이상 DeepSpeed에서 사용할 수 없습니다. `model.load_state_dict(state_dict)`는 모든 딥스피드 마법을 제거하므로 딥스피드 엔진을 다시 초기화해야 합니다. 이 기능은 훈련이 끝날 때만 사용하세요.
+
+
+
+fp32 가중치의 state_dict를 추출하여 로드할 수도 있습니다:
+
+```py
+from deepspeed.utils.zero_to_fp32 import get_fp32_state_dict_from_zero_checkpoint
+
+state_dict = get_fp32_state_dict_from_zero_checkpoint(checkpoint_dir) # cpu에 이미 존재함
+model = model.cpu()
+model.load_state_dict(state_dict)
+```
+
+### 오프라인 환경[[offline]]
+
+DeepSpeed는 언제든지 가중치를 추출할 수 있도록 체크포인트 폴더의 최상위 레벨에 zero_to_fp32.py 스크립트를 제공합니다. 이 스크립트는 독립형 스크립트로 구성 파일이나 [`Trainer`]가 필요하지 않습니다.
+
+예를 들어 체크포인트 폴더가 다음과 같은 경우입니다:
+
+```bash
+$ ls -l output_dir/checkpoint-1/
+-rw-rw-r-- 1 stas stas 1.4K Mar 27 20:42 config.json
+drwxrwxr-x 2 stas stas 4.0K Mar 25 19:52 global_step1/
+-rw-rw-r-- 1 stas stas 12 Mar 27 13:16 latest
+-rw-rw-r-- 1 stas stas 827K Mar 27 20:42 optimizer.pt
+-rw-rw-r-- 1 stas stas 231M Mar 27 20:42 pytorch_model.bin
+-rw-rw-r-- 1 stas stas 623 Mar 27 20:42 scheduler.pt
+-rw-rw-r-- 1 stas stas 1.8K Mar 27 20:42 special_tokens_map.json
+-rw-rw-r-- 1 stas stas 774K Mar 27 20:42 spiece.model
+-rw-rw-r-- 1 stas stas 1.9K Mar 27 20:42 tokenizer_config.json
+-rw-rw-r-- 1 stas stas 339 Mar 27 20:42 trainer_state.json
+-rw-rw-r-- 1 stas stas 2.3K Mar 27 20:42 training_args.bin
+-rwxrw-r-- 1 stas stas 5.5K Mar 27 13:16 zero_to_fp32.py*
+```
+
+딥스피드 체크포인트(ZeRO-2 또는 ZeRO-3) 하위 폴더 `global_step1`에서 fp32 가중치를 재구성하려면 다음 명령을 실행하여 여러 GPU의 전체 fp32 가중치를 단일 pytorch_model.bin 파일로 생성하고 통합합니다. 스크립트는 자동으로 체크포인트가 포함된 하위 폴더를 찾습니다.
+
+```py
+python zero_to_fp32.py . pytorch_model.bin
+```
+
+
+
+자세한 사용법은 `python zero_to_fp32.py -h`를 실행하세요. 이 스크립트에는 최종 fp32 가중치의 2배의 일반 RAM이 필요합니다.
+
+
+
+
+
+
+## ZeRO Inference[[zero-inference]]
+
+[ZeRO Inference](https://www.deepspeed.ai/2022/09/09/zero-inference.html)는 모델 가중치를 CPU 또는 NVMe 메모리에 배치하여 GPU에 부담을 주지 않으므로 GPU에서 대규모 모델을 사용하여 추론을 실행할 수 있습니다. 추론은 최적화 상태 및 그레이디언트에 많은 양의 메모리를 추가로 필요로 하지 않으므로 동일한 하드웨어에 훨씬 더 큰 배치 및/또는 시퀀스 길이를 맞출 수 있습니다.
+
+ZeRO Inference는 [ZeRO-3](#zero-configuration)와 동일한 구성 파일을 공유하며, ZeRO-2 및 ZeRO-1 구성은 추론에 아무런 이점을 제공하지 않으므로 작동하지 않습니다.
+
+ZeRO Inference를 실행하려면 일반적인 훈련 인수를 [`TrainingArguments`] 클래스에 전달하고 `--do_eval` 인수를 추가합니다.
+
+```bash
+deepspeed --num_gpus=2 your_program.py --do_eval --deepspeed ds_config.json
+```
+
+## Trainer 없이 DeepSpeed 사용하기[[non-trainer-deepspeed-integration]]
+
+DeepSpeed는 [`Trainer`] 클래스가 없는 트랜스포머에서도 작동합니다. 이는 [`~PreTrainedModel.from_pretrained`]를 호출할 때 ZeRO-3 매개변수를 수집하고 모델을 여러 GPU에 분할하는 작업만 처리하는 [`HfDeepSpeedConfig`]가 처리합니다.
+
+
+
+모든 것이 자동으로 처리되기를 원한다면, [`Trainer`]와 함께 DeepSpeed를 사용해 보세요! [DeepSpeed 문서](https://www.deepspeed.ai/)를 참조하여 설정 파일에서 매개변수 값을 수동으로 구성해야 합니다(`"auto"` 값은 사용할 수 없음).
+
+
+
+ZeRO-3를 효율적으로 배포하려면 모델 앞에 [`HfDeepSpeedConfig`] 객체를 인스턴스화하고 해당 객체를 유지해야 합니다:
+
+
+
+
+```py
+from transformers.integrations import HfDeepSpeedConfig
+from transformers import AutoModel
+import deepspeed
+
+ds_config = {...} # deepspeed 설정 객체 또는 파일 경로
+# Zero 3를 감지하기 위해 모델을 인스턴스화하기 전에 반드시 실행해야 합니다
+dschf = HfDeepSpeedConfig(ds_config) # 이 객체를 유지하세요.
+model = AutoModel.from_pretrained("openai-community/gpt2")
+engine = deepspeed.initialize(model=model, config_params=ds_config, ...)
+```
+
+
+
+
+[`HfDeepSpeedConfig`] is not required for ZeRO-1 or ZeRO-2.
+
+```py
+from transformers.integrations import HfDeepSpeedConfig
+from transformers import AutoModel, AutoConfig
+import deepspeed
+
+ds_config = {...} # deepspeed 설정 객체 또는 파일 경로
+# Zero 3를 감지하기 위해 모델을 인스턴스화하기 전에 반드시 실행해야 합니다
+dschf = HfDeepSpeedConfig(ds_config) # 이 객체를 유지하세요.
+config = AutoConfig.from_pretrained("openai-community/gpt2")
+model = AutoModel.from_config(config)
+engine = deepspeed.initialize(model=model, config_params=ds_config, ...)
+```
+
+
+
+
+### Trainer 없이 ZeRO Inference 사용하기[[non-trainer-zero-inference]]
+
+단일 GPU에 모델을 맞출 수 없는 경우 [`Trainer`]없이 ZeRO 추론을 실행하려면 추가 GPU를 사용하거나 CPU 메모리로 오프로드를 시도하세요. 여기서 이해해야 할 중요한 뉘앙스는 ZeRO가 설계된 방식에 따라 서로 다른 GPU에서 서로 다른 입력을 병렬로 처리할 수 있다는 것입니다.
+
+반드시 확인하세요:
+
+* GPU 메모리가 충분한 경우 CPU 오프로드를 비활성화합니다(속도가 느려지므로).
+* Ampere 이상의 GPU를 사용하는 경우 bf16을 활성화하면 속도가 빨라집니다. 이러한 GPU가 없는 경우 오버플로 오류가 발생할 수 있으므로 bf16으로 사전 학습된 모델(T5 모델)을 사용하지 않는 한 fp16을 활성화할 수 있습니다.
+
+단일 GPU에 맞지 않는 모델에서 [`Trainer`] 없이 ZeRO 추론을 실행하는 방법에 대한 더 나은 아이디어를 얻으려면 다음 스크립트를 살펴보시기 바랍니다.
+
+```py
+#!/usr/bin/env python
+
+# 이 스크립트는 단일 GPU에 모델을 맞출 수 없을 때 추론 모드에서 Deepspeed ZeRO를 사용하는 방법을 보여줍니다.
+#
+# 1. CPU 오프로드와 함께 1개의 GPU 사용
+# 2. 또는 여러 GPU 사용
+#
+# 먼저 deepspeed를 설치해야 합니다: pip install deepspeed
+#
+# 여기서는 약 15GB의 GPU RAM이 필요한 3B "bigscience/T0_3B" 모델을 사용합니다 - 따라서 1개의 큰 GPU나 2개의
+# 작은 GPU로 처리할 수 있습니다. 또는 1개의 작은 GPU와 많은 CPU 메모리로도 가능합니다.
+#
+# 약 50GB가 필요한 "bigscience/T0"와 같은 더 큰 모델을 사용하려면, 80GB GPU가 없는 한
+# 2-4개의 GPU가 필요할 것입니다. 그리고 여러 입력을 한 번에 처리하고 싶다면
+# 스크립트를 수정하여 더 많은 GPU를 처리할 수 있습니다.
+#
+# 제공된 deepspeed 설정은 CPU 메모리 오프로딩도 활성화하므로, 사용 가능한 CPU 메모리가 많고
+# 속도 저하를 감수할 수 있다면 일반적으로 단일 GPU에 맞지 않는 모델을 로드할 수 있을 것입니다.
+# GPU 메모리가 충분하다면 CPU로의 오프로드를 원하지 않을 때 프로그램이 더 빠르게 실행될 것입니다 - 그럴 때는 해당 섹션을 비활성화하세요.
+#
+# 1개의 GPU에 배포하려면:
+#
+# deepspeed --num_gpus 1 t0.py
+# 또는:
+# python -m torch.distributed.run --nproc_per_node=1 t0.py
+#
+# 2개의 GPU에 배포하려면:
+#
+# deepspeed --num_gpus 2 t0.py
+# 또는:
+# python -m torch.distributed.run --nproc_per_node=2 t0.py
+
+from transformers import AutoTokenizer, AutoConfig, AutoModelForSeq2SeqLM
+from transformers.integrations import HfDeepSpeedConfig
+import deepspeed
+import os
+import torch
+
+os.environ["TOKENIZERS_PARALLELISM"] = "false" # 토크나이저의 병렬 처리에 관한 경고를 피하기 위함입니다.
+
+# 분산 환경 설정
+local_rank = int(os.getenv("LOCAL_RANK", "0"))
+world_size = int(os.getenv("WORLD_SIZE", "1"))
+torch.cuda.set_device(local_rank)
+deepspeed.init_distributed()
+
+model_name = "bigscience/T0_3B"
+
+config = AutoConfig.from_pretrained(model_name)
+model_hidden_size = config.d_model
+
+# 배치 크기는 world_size로 나누어 떨어져야 하지만, world_size보다 클 수 있습니다
+train_batch_size = 1 * world_size
+
+# ds_config 참고사항
+#
+# - Ampere 이상의 GPU를 사용하는 경우 bf16을 활성화하세요 - 이는 혼합 정밀도로 실행되어
+# 더 빠를 것입니다.
+#
+# - 오래된 GPU의 경우 fp16을 활성화할 수 있지만, bf16으로 사전 훈련되지 않은 모델에서만 작동합니다 - 예를 들어
+# 모든 공식 t5 모델은 bf16으로 사전 훈련되었습니다
+#
+# - CPU 오프로드를 원하지 않는다면 offload_param.device를 "none"으로 설정하거나 `offload_param` 섹션을
+# 완전히 제거하세요
+#
+# - `offload_param`을 사용하는 경우, stage3_param_persistence_threshold를 수동으로 미세 조정하여
+# 어떤 매개변수가 GPU에 남아있어야 하는지 제어할 수 있습니다 - 값이 클수록 오프로드 크기가 작아집니다
+#
+# Deepspeed 설정에 대한 자세한 정보는 다음을 참조하세요
+# https://huggingface.co/docs/transformers/main/main_classes/deepspeed
+
+# 일관성을 위해 json과 동일한 형식을 유지하되, true/false에는 소문자를 사용합니다
+# fmt: off
+ds_config = {
+ "fp16": {
+ "enabled": False
+ },
+ "bf16": {
+ "enabled": False
+ },
+ "zero_optimization": {
+ "stage": 3,
+ "offload_param": {
+ "device": "cpu",
+ "pin_memory": True
+ },
+ "overlap_comm": True,
+ "contiguous_gradients": True,
+ "reduce_bucket_size": model_hidden_size * model_hidden_size,
+ "stage3_prefetch_bucket_size": 0.9 * model_hidden_size * model_hidden_size,
+ "stage3_param_persistence_threshold": 10 * model_hidden_size
+ },
+ "steps_per_print": 2000,
+ "train_batch_size": train_batch_size,
+ "train_micro_batch_size_per_gpu": 1,
+ "wall_clock_breakdown": False
+}
+# fmt: on
+
+# 다음 줄은 모델의 `from_pretrained` 메소드가 호출될 때
+# deepspeed.zero.Init를 사용하여 모델을 여러 GPU에 직접 분할하도록 transformers에 지시합니다.
+#
+# **이는 AutoModelForSeq2SeqLM.from_pretrained(model_name)로 모델을 로드하기 전에 실행되어야 합니다**
+#
+# 그렇지 않으면 모델이 먼저 정상적으로 로드된 후 포워드 시에만 분할되는데, 이는
+# 덜 효율적이며 CPU RAM이 부족할 경우 실패할 수 있습니다
+dschf = HfDeepSpeedConfig(ds_config) # 이 객체를 유지하세요
+
+# 이제 모델을 로드할 수 있습니다.
+model = AutoModelForSeq2SeqLM.from_pretrained(model_name)
+
+# Deepspeed ZeRO를 초기화하고 엔진 객체만 저장
+ds_engine = deepspeed.initialize(model=model, config_params=ds_config)[0]
+ds_engine.module.eval() # inference
+
+# Deepspeed ZeRO는 각 GPU에서 서로 관련 없는 입력을 처리할 수 있습니다. 따라서 2개의 GPU를 사용하면 한 번에 2개의 입력을 처리할 수 있습니다.
+# GPU를 더 많이 사용하는 경우 그에 맞게 조정하세요.
+
+# 물론 처리할 입력이 하나뿐이라면 두 GPU에 동일한 문자열을 전달해야 합니다.
+# GPU를 하나만 사용하는 경우에는 rank 0만 갖게 됩니다.
+rank = torch.distributed.get_rank()
+if rank == 0:
+ text_in = "Is this review positive or negative? Review: this is the best cast iron skillet you will ever buy"
+elif rank == 1:
+ text_in = "Is this review positive or negative? Review: this is the worst restaurant ever"
+
+tokenizer = AutoTokenizer.from_pretrained(model_name)
+inputs = tokenizer.encode(text_in, return_tensors="pt").to(device=local_rank)
+with torch.no_grad():
+ outputs = ds_engine.module.generate(inputs, synced_gpus=True)
+text_out = tokenizer.decode(outputs[0], skip_special_tokens=True)
+print(f"rank{rank}:\n in={text_in}\n out={text_out}")
+```
+
+스크립트를 t0.py로 저장하고 실행합니다:
+
+```bash
+$ deepspeed --num_gpus 2 t0.py
+rank0:
+ in=Is this review positive or negative? Review: this is the best cast iron skillet you will ever buy
+ out=Positive
+rank1:
+ in=Is this review positive or negative? Review: this is the worst restaurant ever
+ out=negative
+```
+
+이것은 매우 기본적인 예시이므로 사용 사례에 맞게 조정할 수 있습니다.
+
+### 생성[[generate]]
+
+생성에 ZeRO-3와 함께 여러 개의 GPU를 사용하려면 [`~GenerationMixin.generate`] 메서드에서 `synced_gpus=True`를 설정하여 GPU를 동기화해야 합니다. 그렇지 않으면 한 GPU가 다른 GPU보다 먼저 생성을 완료하면 나머지 GPU가 먼저 완료한 GPU로부터 가중치 샤드를 받지 못하여 전체 시스템이 중단됩니다.
+
+트랜스포머>=4.28의 경우, 생성 중에 여러 개의 GPU가 감지되면 `synced_gpus`가 자동으로 `True`로 설정됩니다.
+
+## 트러블슈팅[[troubleshoot]]
+
+문제가 발생하면 DeepSpeed가 문제의 원인이 아닌 경우가 많으므로(아주 명백하고 예외적으로 DeepSpeed 모듈을 볼 수 있는 경우가 아니라면) DeepSpeed가 문제의 원인인지 고려해야 합니다! 첫 번째 단계는 DeepSpeed 없이 설정을 다시 시도하고 문제가 지속되면 문제를 신고하는 것입니다. 문제가 핵심적인 DeepSpeed 문제이고 transformers와 관련이 없는 경우, [DeepSpeed 리포지토리](https://github.com/deepspeedai/DeepSpeed)에서 이슈를 개설하세요.
+
+transformers와 관련된 이슈를 개설할 때에는 다음 정보를 제공해 주세요:
+
+* 전체 DeepSpeed 구성 파일
+
+*[`Trainer`]의 명령줄 인수, 또는[`Trainer`] 설정을 직접 작성하는 경우[`TrainingArguments`] 인수(관련 없는 항목이 수십 개 있는 [`TrainingArguments`]는 덤프하지 마세요).
+
+* 다음 코드의 출력 결과:
+
+```bash
+python -c 'import torch; print(f"torch: {torch.__version__}")'
+python -c 'import transformers; print(f"transformers: {transformers.__version__}")'
+python -c 'import deepspeed; print(f"deepspeed: {deepspeed.__version__}")'
+```
+
+* 문제를 재현할 수 있는 Google Colab 노트북 링크
+
+* 불가능할 경우 기존 예제를 사용하여 문제를 재현할 수 있는 표준 및 사용자 지정이 아닌 데이터 집합을 사용할 수 있습니다.
+
+다음 섹션에서는 가장 일반적인 두 가지 문제를 해결하기 위한 가이드를 제공합니다.
+
+### DeepSpeed 프로세스가 시작 단계에서 종료되었을 경우[[deepspeed-process-killed-at-startup]]
+
+실행 중에 트레이스백 없이 DeepSpeed 프로세스가 종료되면 일반적으로 프로그램이 시스템보다 많은 CPU 메모리를 할당하려고 시도했거나 프로세스가 허용된 것보다 많은 CPU 메모리를 할당하려고 시도하여 OS 커널이 프로세스를 종료했음을 의미합니다. 이 경우 구성 파일에 `offload_optimizer`, `offload_param` 또는 둘 다 CPU로 오프로드하도록 구성되어 있는지 확인하세요.
+
+NVMe 및 ZeRO-3를 설정한 경우 NVMe로 오프로드를 실험해 보세요(모델의 메모리 요구 사항을 [확인](https://deepspeed.readthedocs.io/en/latest/memory.html)하세요).
+
+### NaN 손실[[nan-loss]]
+
+모델을 bf16으로 사전 훈련한 다음 fp16으로 사용하려고 할 때 NaN 손실이 발생하는 경우가 많습니다(특히 TPU 훈련 모델에 해당). 이 문제를 해결하려면 하드웨어가 이를 지원하는 경우(TPU, Ampere GPU 이상) fp32 또는 bf16을 사용하세요.
+
+다른 문제는 fp16 사용과 관련이 있을 수 있습니다. 예를 들어 이것이 fp16 구성인 경우입니다:
+
+```yaml
+{
+ "fp16": {
+ "enabled": "auto",
+ "loss_scale": 0,
+ "loss_scale_window": 1000,
+ "initial_scale_power": 16,
+ "hysteresis": 2,
+ "min_loss_scale": 1
+ }
+}
+```
+
+로그에 다음과 같은 `OVERFLOW!` 메시지가 표시될 수 있습니다:
+
+```bash
+0%| | 0/189 [00:00
+
+# 🤗 Tokenizers 라이브러리의 토크나이저 사용하기[[use-tokenizers-from-tokenizers]]
+
+[`PreTrainedTokenizerFast`]는 [🤗 Tokenizers](https://huggingface.co/docs/tokenizers) 라이브러리에 기반합니다. 🤗 Tokenizers 라이브러리의 토크나이저는
+🤗 Transformers로 매우 간단하게 불러올 수 있습니다.
+
+구체적인 내용에 들어가기 전에, 몇 줄의 코드로 더미 토크나이저를 만들어 보겠습니다:
+
+```python
+>>> from tokenizers import Tokenizer
+>>> from tokenizers.models import BPE
+>>> from tokenizers.trainers import BpeTrainer
+>>> from tokenizers.pre_tokenizers import Whitespace
+
+>>> tokenizer = Tokenizer(BPE(unk_token="[UNK]"))
+>>> trainer = BpeTrainer(special_tokens=["[UNK]", "[CLS]", "[SEP]", "[PAD]", "[MASK]"])
+
+>>> tokenizer.pre_tokenizer = Whitespace()
+>>> files = [...]
+>>> tokenizer.train(files, trainer)
+```
+
+우리가 정의한 파일을 통해 이제 학습된 토크나이저를 갖게 되었습니다. 이 런타임에서 계속 사용하거나 JSON 파일로 저장하여 나중에 사용할 수 있습니다.
+
+## 토크나이저 객체로부터 직접 불러오기[[loading-directly-from-the-tokenizer-object]]
+
+🤗 Transformers 라이브러리에서 이 토크나이저 객체를 활용하는 방법을 살펴보겠습니다.
+[`PreTrainedTokenizerFast`] 클래스는 인스턴스화된 *토크나이저* 객체를 인수로 받아 쉽게 인스턴스화할 수 있습니다:
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_object=tokenizer)
+```
+
+이제 `fast_tokenizer` 객체는 🤗 Transformers 토크나이저에서 공유하는 모든 메소드와 함께 사용할 수 있습니다! 자세한 내용은 [토크나이저 페이지](main_classes/tokenizer)를 참조하세요.
+
+## JSON 파일에서 불러오기[[loading-from-a-JSON-file]]
+
+
+
+JSON 파일에서 토크나이저를 불러오기 위해, 먼저 토크나이저를 저장해 보겠습니다:
+
+```python
+>>> tokenizer.save("tokenizer.json")
+```
+
+JSON 파일을 저장한 경로는 `tokenizer_file` 매개변수를 사용하여 [`PreTrainedTokenizerFast`] 초기화 메소드에 전달할 수 있습니다:
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_file="tokenizer.json")
+```
+
+이제 `fast_tokenizer` 객체는 🤗 Transformers 토크나이저에서 공유하는 모든 메소드와 함께 사용할 수 있습니다! 자세한 내용은 [토크나이저 페이지](main_classes/tokenizer)를 참조하세요.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/fsdp.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/fsdp.md
new file mode 100644
index 0000000000000000000000000000000000000000..bab1fda71b4ed10542aea99837bbd06154abd888
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/fsdp.md
@@ -0,0 +1,138 @@
+
+
+# 완전 분할 데이터 병렬 처리(FSDP) [[fully-sharded-data-parallel]]
+
+[Fully Sharded Data Parallel (FSDP)](https://pytorch.org/blog/introducing-pytorch-fully-sharded-data-parallel-api/)은 모델의 매개변수, 그레이디언트 및 옵티마이저 상태를 사용 가능한 GPU(작업자 또는 *랭크*라고도 함) 수에 따라 분할하는 데이터 병렬 처리 방식입니다. [DistributedDataParallel (DDP)](https://pytorch.org/docs/stable/generated/torch.nn.parallel.DistributedDataParallel.html)와 달리, FSDP는 각 GPU에 모델을 복제하기 때문에 메모리 사용량을 줄입니다. 이는 GPU 메모리 효율성을 향상시키며 적은 수의 GPU로 훨씬 더 큰 모델을 훈련할 수 있게 합니다. FSDP는 분산 환경에서의 훈련을 쉽게 관리할 수 있는 라이브러리인 Accelerate와 통합되어 있으며, 따라서 [`Trainer`] 클래스에서 사용할 수 있습니다.
+
+시작하기 전에 Accelerate가 설치되어 있고 최소 PyTorch 2.1.0 이상의 버전이 설치되어 있는지 확인하세요.
+
+```bash
+pip install accelerate
+```
+
+## FSDP 구성 [[fsdp-configuration]]
+
+시작하려면 [`accelerate config`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-config) 명령을 실행하여 훈련 환경에 대한 구성 파일을 생성하세요. Accelerate는 이 구성 파일을 사용하여 `accelerate config`에서 선택한 훈련 옵션에 따라 자동으로 올바른 훈련 환경을 설정합니다.
+
+```bash
+accelerate config
+```
+
+`accelerate config`를 실행하면 훈련 환경을 구성하기 위한 일련의 옵션들이 나타납니다. 이 섹션에서는 가장 중요한 FSDP 옵션 중 일부를 다룹니다. 다른 사용 가능한 FSDP 옵션에 대해 더 알아보고 싶다면 [fsdp_config](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.fsdp_config) 매개변수를 참조하세요.
+
+### 분할 전략 [[sharding-strategy]]
+
+FSDP는 여러 가지 분할 전략을 제공합니다:
+
+* `FULL_SHARD` - 모델 매개변수, 그레이디언트 및 옵티마이저 상태를 작업자 간에 분할; 이 옵션을 선택하려면 `1`을 선택하세요
+* `SHARD_GRAD_OP` - 그레이디언트 및 옵티마이저 상태를 작업자 간에 분할; 이 옵션을 선택하려면 `2`를 선택하세요
+* `NO_SHARD` - 아무 것도 분할하지 않음 (DDP와 동일); 이 옵션을 선택하려면 `3`을 선택하세요
+* `HYBRID_SHARD` - 각 작업자가 전체 복사본을 가지고 있는 상태에서 모델 매개변수, 그레이디언트 및 옵티마이저 상태를 작업자 내에서 분할; 이 옵션을 선택하려면 `4`를 선택하세요
+* `HYBRID_SHARD_ZERO2` - 각 작업자가 전체 복사본을 가지고 있는 상태에서 그레이디언트 및 옵티마이저 상태를 작업자 내에서 분할; 이 옵션을 선택하려면 `5`를 선택하세요
+
+이것은 `fsdp_sharding_strategy` 플래그로 활성화됩니다.
+
+### CPU 오프로드 [[cpu-offload]]
+
+사용하지 않는 매개변수와 그레이디언트를 CPU로 오프로드하여 더 많은 GPU 메모리를 절약하고 FSDP로도 충분하지 않은 큰 모델을 GPU에 적재할 수 있도록 할 수 있습니다. 이는 `accelerate config`를 실행할 때 `fsdp_offload_params: true`로 설정하여 활성화됩니다.
+
+### 래핑 정책 [[wrapping-policy]]
+
+FSDP는 네트워크의 각 레이어를 래핑하여 적용됩니다. 래핑은 일반적으로 중첩 방식으로 적용되며 각각 순방향으로 지나간 후 전체 가중치를 삭제하여 다음 레이어에서 사용할 메모리를 절약합니다. *자동 래핑* 정책은 이를 구현하는 가장 간단한 방법이며 코드를 변경할 필요가 없습니다. Transformer 레이어를 래핑하려면 `fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP`를 선택하고 래핑할 레이어를 지정하려면 `fsdp_transformer_layer_cls_to_wrap`를 선택하세요 (예: `BertLayer`).
+
+또는 특정 매개변수 수를 초과할 경우 FSDP가 레이어에 적용되는 크기 기반 래핑 정책을 선택할 수 있습니다. 이는 `fsdp_wrap_policy: SIZE_BASED_WRAP` 및 `min_num_param`을 원하는 크기의 임계값으로 설정하여 활성화됩니다.
+
+### 체크포인트 [[checkpointing]]
+
+중간 체크포인트는 `fsdp_state_dict_type: SHARDED_STATE_DICT`로 저장해야 합니다. CPU 오프로드가 활성화된 랭크 0에서 전체 상태 딕셔너리를 저장하는 데 시간이 많이 걸리고, 브로드캐스팅 중 무기한 대기하여 `NCCL Timeout` 오류가 발생할 수 있기 때문입니다. [`~accelerate.Accelerator.load_state`] 메서드를 사용하여 분할된 상태 딕셔너리로 훈련을 재개할 수 있습니다.
+
+```py
+# 경로가 내재된 체크포인트
+accelerator.load_state("ckpt")
+```
+
+그러나 훈련이 끝나면 전체 상태 딕셔너리를 저장해야 합니다. 분할된 상태 딕셔너리는 FSDP와만 호환되기 때문입니다.
+
+```py
+if trainer.is_fsdp_enabled:
+ trainer.accelerator.state.fsdp_plugin.set_state_dict_type("FULL_STATE_DICT")
+
+trainer.save_model(script_args.output_dir)
+```
+
+### TPU [[tpu]]
+
+[PyTorch XLA](https://pytorch.org/xla/release/2.1/index.html)는 TPU에 대한 FSDP 훈련을 지원하며 `accelerate config`로 생성된 FSDP 구성 파일을 수정하여 활성화할 수 있습니다. 위에서 지정한 분할 전략 및 래핑 옵션 외에도 아래에 표시된 매개변수를 파일에 추가할 수 있습니다.
+
+```yaml
+xla: True # PyTorch/XLA를 활성화하려면 True로 설정해야 합니다
+xla_fsdp_settings: # XLA 특정 FSDP 매개변수
+xla_fsdp_grad_ckpt: True # gradient checkpointing을 사용합니다
+```
+
+[`xla_fsdp_settings`](https://github.com/pytorch/xla/blob/2e6e183e0724818f137c8135b34ef273dea33318/torch_xla/distributed/fsdp/xla_fully_sharded_data_parallel.py#L128)는 FSDP에 대한 추가적인 XLA 특정 매개변수를 구성할 수 있게 합니다.
+
+## 훈련 시작 [[launch-training]]
+
+예시 FSDP 구성 파일은 다음과 같을 수 있습니다:
+
+```yaml
+compute_environment: LOCAL_MACHINE
+debug: false
+distributed_type: FSDP
+downcast_bf16: 'no'
+fsdp_config:
+ fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
+ fsdp_backward_prefetch_policy: BACKWARD_PRE
+ fsdp_cpu_ram_efficient_loading: true
+ fsdp_forward_prefetch: false
+ fsdp_offload_params: true
+ fsdp_sharding_strategy: 1
+ fsdp_state_dict_type: SHARDED_STATE_DICT
+ fsdp_sync_module_states: true
+ fsdp_transformer_layer_cls_to_wrap: BertLayer
+ fsdp_use_orig_params: true
+machine_rank: 0
+main_training_function: main
+mixed_precision: bf16
+num_machines: 1
+num_processes: 2
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+훈련을 시작하려면 [`accelerate launch`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-launch) 명령을 실행하세요. 이 때 전에 `accelerate config`로 생성한 구성 파일을 자동으로 사용합니다.
+
+```bash
+accelerate launch my-trainer-script.py
+```
+
+```bash
+accelerate launch --fsdp="full shard" --fsdp_config="path/to/fsdp_config/ my-trainer-script.py
+```
+
+## 다음 단계 [[next-steps]]
+
+FSDP는 매우 큰 모델을 훈련할 때 강력한 도구가 될 수 있으며, 여러 개의 GPU나 TPU를 사용할 수 있습니다. 모델 매개변수, 옵티마이저 및 그레이디언트 상태를 분할하고 비활성 상태일 때, CPU로 오프로드하면 FSDP는 대규모 훈련의 높은 연산 비용을 줄일 수 있습니다. 더 알아보고 싶다면 다음 자료가 도움이 될 수 있습니다:
+
+* [FSDP](https://huggingface.co/docs/accelerate/usage_guides/fsdp)에 대한 더 깊이 있는 Accelerate 가이드를 따라가 보세요.
+* [PyTorch의 완전 분할 데이터 병렬 처리 (FSDP) API를 소개합니다](https://pytorch.org/blog/introducing-pytorch-fully-sharded-data-parallel-api/) 블로그 글을 읽어보세요.
+* [FSDP를 사용하여 클라우드 TPU에서 PyTorch 모델 크기 조절하기](https://pytorch.org/blog/scaling-pytorch-models-on-cloud-tpus-with-fsdp/) 블로그 글을 읽어보세요.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/generation_strategies.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/generation_strategies.md
new file mode 100644
index 0000000000000000000000000000000000000000..05f81c008b30f153932258968ed72c01888e35f2
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/generation_strategies.md
@@ -0,0 +1,337 @@
+
+
+# Text generation strategies[[text-generation-strategies]]
+
+텍스트 생성은 개방형 텍스트 작성, 요약, 번역 등 다양한 자연어 처리(NLP) 작업에 필수적입니다. 이는 또한 음성-텍스트 변환, 시각-텍스트 변환과 같이 텍스트를 출력으로 하는 여러 혼합 모달리티 응용 프로그램에서도 중요한 역할을 합니다. 텍스트 생성을 가능하게 하는 몇몇 모델로는 GPT2, XLNet, OpenAI GPT, CTRL, TransformerXL, XLM, Bart, T5, GIT, Whisper 등이 있습니다.
+
+
+[`~generation.GenerationMixin.generate`] 메서드를 활용하여 다음과 같은 다양한 작업들에 대해 텍스트 결과물을 생성하는 몇 가지 예시를 살펴보세요:
+* [텍스트 요약](./tasks/summarization#inference)
+* [이미지 캡셔닝](./model_doc/git#transformers.GitForCausalLM.forward.example)
+* [오디오 전사](./model_doc/whisper#transformers.WhisperForConditionalGeneration.forward.example)
+
+generate 메소드에 입력되는 값들은 모델의 데이터 형태에 따라 달라집니다. 이 값들은 AutoTokenizer나 AutoProcessor와 같은 모델의 전처리 클래스에 의해 반환됩니다. 모델의 전처리 장치가 하나 이상의 입력 유형을 생성하는 경우, 모든 입력을 generate()에 전달해야 합니다. 각 모델의 전처리 장치에 대해서는 해당 모델의 문서에서 자세히 알아볼 수 있습니다.
+
+텍스트를 생성하기 위해 출력 토큰을 선택하는 과정을 디코딩이라고 하며, `generate()` 메소드가 사용할 디코딩 전략을 사용자가 커스터마이징할 수 있습니다. 디코딩 전략을 수정하는 것은 훈련 가능한 매개변수의 값들을 변경하지 않지만, 생성된 출력의 품질에 눈에 띄는 영향을 줄 수 있습니다. 이는 텍스트에서 반복을 줄이고, 더 일관성 있게 만드는 데 도움을 줄 수 있습니다.
+
+
+이 가이드에서는 다음과 같은 내용을 다룹니다:
+* 기본 생성 설정
+* 일반적인 디코딩 전략과 주요 파라미터
+* 🤗 Hub에서 미세 조정된 모델과 함께 사용자 정의 생성 설정을 저장하고 공유하는 방법
+
+## 기본 텍스트 생성 설정[[default-text-generation-configuration]]
+
+모델의 디코딩 전략은 생성 설정에서 정의됩니다. 사전 훈련된 모델을 [`pipeline`] 내에서 추론에 사용할 때, 모델은 내부적으로 기본 생성 설정을 적용하는 `PreTrainedModel.generate()` 메소드를 호출합니다. 사용자가 모델과 함께 사용자 정의 설정을 저장하지 않았을 경우에도 기본 설정이 사용됩니다.
+
+모델을 명시적으로 로드할 때, `model.generation_config`을 통해 제공되는 생성 설정을 검사할 수 있습니다.
+
+```python
+>>> from transformers import AutoModelForCausalLM
+
+>>> model = AutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+>>> model.generation_config
+GenerationConfig {
+ "bos_token_id": 50256,
+ "eos_token_id": 50256,
+}
+```
+
+ `model.generation_config`를 출력하면 기본 설정과 다른 값들만 표시되고, 기본값들은 나열되지 않습니다.
+
+기본 생성 설정은 입력 프롬프트와 출력을 합친 최대 크기를 20 토큰으로 제한하여 리소스 부족을 방지합니다. 기본 디코딩 전략은 탐욕 탐색(greedy search)으로, 다음 토큰으로 가장 높은 확률을 가진 토큰을 선택하는 가장 단순한 디코딩 전략입니다. 많은 작업과 작은 출력 크기에 대해서는 이 방법이 잘 작동하지만, 더 긴 출력을 생성할 때 사용하면 매우 반복적인 결과를 생성하게 될 수 있습니다.
+
+## 텍스트 생성 사용자 정의[[customize-text-generation]]
+
+파라미터와 해당 값을 [`generate`] 메소드에 직접 전달하여 `generation_config`을 재정의할 수 있습니다:
+
+```python
+>>> my_model.generate(**inputs, num_beams=4, do_sample=True) # doctest: +SKIP
+```
+
+기본 디코딩 전략이 대부분의 작업에 잘 작동한다 하더라도, 조정할 수 있는 몇 가지 파라미터가 있습니다. 일반적으로 조정되는 파라미터에는 다음과 같은 것들이 포함됩니다:
+
+- `max_new_tokens`: 생성할 최대 토큰 수입니다. 즉, 프롬프트에 있는 토큰을 제외한 출력 시퀀스의 크기입니다. 출력의 길이를 중단 기준으로 사용하는 대신, 전체 생성물이 일정 시간을 초과할 때 생성을 중단하기로 선택할 수도 있습니다. 더 알아보려면 [`StoppingCriteria`]를 확인하세요.
+- `num_beams`: 1보다 큰 수의 빔을 지정함으로써, 탐욕 탐색(greedy search)에서 빔 탐색(beam search)으로 전환하게 됩니다. 이 전략은 각 시간 단계에서 여러 가설을 평가하고 결국 전체 시퀀스에 대해 가장 높은 확률을 가진 가설을 선택합니다. 이는 초기 토큰의 확률이 낮아 탐욕 탐색에 의해 무시되었을 높은 확률의 시퀀스를 식별할 수 있는 장점을 가집니다.
+- `do_sample`: 이 매개변수를 `True`로 설정하면, 다항 샘플링, 빔 탐색 다항 샘플링, Top-K 샘플링 및 Top-p 샘플링과 같은 디코딩 전략을 활성화합니다. 이러한 전략들은 전체 어휘에 대한 확률 분포에서 다음 토큰을 선택하며, 전략별로 특정 조정이 적용됩니다.
+- `num_return_sequences`: 각 입력에 대해 반환할 시퀀스 후보의 수입니다. 이 옵션은 빔 탐색(beam search)의 변형과 샘플링과 같이 여러 시퀀스 후보를 지원하는 디코딩 전략에만 사용할 수 있습니다. 탐욕 탐색(greedy search)과 대조 탐색(contrastive search) 같은 디코딩 전략은 단일 출력 시퀀스를 반환합니다.
+
+## 모델에 사용자 정의 디코딩 전략 저장[[save-a-custom-decoding-strategy-with-your-model]]
+
+특정 생성 설정을 가진 미세 조정된 모델을 공유하고자 할 때, 다음 단계를 따를 수 있습니다:
+* [`GenerationConfig`] 클래스 인스턴스를 생성합니다.
+* 디코딩 전략 파라미터를 설정합니다.
+* 생성 설정을 [`GenerationConfig.save_pretrained`]를 사용하여 저장하며, `config_file_name` 인자는 비워둡니다.
+* 모델의 저장소에 설정을 업로드하기 위해 `push_to_hub`를 `True`로 설정합니다.
+
+```python
+>>> from transformers import AutoModelForCausalLM, GenerationConfig
+
+>>> model = AutoModelForCausalLM.from_pretrained("my_account/my_model") # doctest: +SKIP
+>>> generation_config = GenerationConfig(
+... max_new_tokens=50, do_sample=True, top_k=50, eos_token_id=model.config.eos_token_id
+... )
+>>> generation_config.save_pretrained("my_account/my_model", push_to_hub=True) # doctest: +SKIP
+```
+
+단일 디렉토리에 여러 생성 설정을 저장할 수 있으며, 이때 [`GenerationConfig.save_pretrained`]의 `config_file_name` 인자를 사용합니다. 나중에 [`GenerationConfig.from_pretrained`]로 이들을 인스턴스화할 수 있습니다. 이는 단일 모델에 대해 여러 생성 설정을 저장하고 싶을 때 유용합니다(예: 샘플링을 이용한 창의적 텍스트 생성을 위한 하나, 빔 탐색을 이용한 요약을 위한 다른 하나 등). 모델에 설정 파일을 추가하기 위해 적절한 Hub 권한을 가지고 있어야 합니다.
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer, GenerationConfig
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-t5/t5-small")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("google-t5/t5-small")
+
+>>> translation_generation_config = GenerationConfig(
+... num_beams=4,
+... early_stopping=True,
+... decoder_start_token_id=0,
+... eos_token_id=model.config.eos_token_id,
+... pad_token=model.config.pad_token_id,
+... )
+
+>>> # 팁: Hub에 push하려면 `push_to_hub=True`를 추가
+>>> translation_generation_config.save_pretrained("/tmp", "translation_generation_config.json")
+
+>>> # 명명된 생성 설정 파일을 사용하여 생성을 매개변수화할 수 있습니다.
+>>> generation_config = GenerationConfig.from_pretrained("/tmp", "translation_generation_config.json")
+>>> inputs = tokenizer("translate English to French: Configuration files are easy to use!", return_tensors="pt")
+>>> outputs = model.generate(**inputs, generation_config=generation_config)
+>>> print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['Les fichiers de configuration sont faciles à utiliser!']
+```
+
+## 스트리밍[[streaming]]
+
+`generate()` 메소드는 `streamer` 입력을 통해 스트리밍을 지원합니다. `streamer` 입력은 `put()`과 `end()` 메소드를 가진 클래스의 인스턴스와 호환됩니다. 내부적으로, `put()`은 새 토큰을 추가하는 데 사용되며, `end()`는 텍스트 생성의 끝을 표시하는 데 사용됩니다.
+
+
+
+스트리머 클래스의 API는 아직 개발 중이며, 향후 변경될 수 있습니다.
+
+
+
+실제로 다양한 목적을 위해 자체 스트리밍 클래스를 만들 수 있습니다! 또한, 기본적인 스트리밍 클래스들도 준비되어 있어 바로 사용할 수 있습니다. 예를 들어, [`TextStreamer`] 클래스를 사용하여 `generate()`의 출력을 화면에 한 단어씩 스트리밍할 수 있습니다:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, TextStreamer
+
+>>> tok = AutoTokenizer.from_pretrained("openai-community/gpt2")
+>>> model = AutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+>>> inputs = tok(["An increasing sequence: one,"], return_tensors="pt")
+>>> streamer = TextStreamer(tok)
+
+>>> # 스트리머는 평소와 같은 출력값을 반환할 뿐만 아니라 생성된 텍스트도 표준 출력(stdout)으로 출력합니다.
+>>> _ = model.generate(**inputs, streamer=streamer, max_new_tokens=20)
+An increasing sequence: one, two, three, four, five, six, seven, eight, nine, ten, eleven,
+```
+
+## 디코딩 전략[[decoding-strategies]]
+
+`generate()` 매개변수와 궁극적으로 `generation_config`의 특정 조합을 사용하여 특정 디코딩 전략을 활성화할 수 있습니다. 이 개념이 처음이라면, 흔히 사용되는 디코딩 전략이 어떻게 작동하는지 설명하는 [이 블로그 포스트](https://huggingface.co/blog/how-to-generate)를 읽어보는 것을 추천합니다.
+
+여기서는 디코딩 전략을 제어하는 몇 가지 매개변수를 보여주고, 이를 어떻게 사용할 수 있는지 설명하겠습니다.
+
+### 탐욕 탐색(Greedy Search)[[greedy-search]]
+
+[`generate`]는 기본적으로 탐욕 탐색 디코딩을 사용하므로 이를 활성화하기 위해 별도의 매개변수를 지정할 필요가 없습니다. 이는 `num_beams`가 1로 설정되고 `do_sample=False`로 되어 있다는 의미입니다."
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> prompt = "I look forward to"
+>>> checkpoint = "distilbert/distilgpt2"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+>>> outputs = model.generate(**inputs)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['I look forward to seeing you all again!\n\n\n\n\n\n\n\n\n\n\n']
+```
+
+### 대조 탐색(Contrastive search)[[contrastive-search]]
+
+2022년 논문 [A Contrastive Framework for Neural Text Generation](https://arxiv.org/abs/2202.06417)에서 제안된 대조 탐색 디코딩 전략은 반복되지 않으면서도 일관된 긴 출력을 생성하는 데 있어 우수한 결과를 보였습니다. 대조 탐색이 작동하는 방식을 알아보려면 [이 블로그 포스트](https://huggingface.co/blog/introducing-csearch)를 확인하세요. 대조 탐색의 동작을 가능하게 하고 제어하는 두 가지 주요 매개변수는 `penalty_alpha`와 `top_k`입니다:
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForCausalLM
+
+>>> checkpoint = "openai-community/gpt2-large"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+
+>>> prompt = "Hugging Face Company is"
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> outputs = model.generate(**inputs, penalty_alpha=0.6, top_k=4, max_new_tokens=100)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Hugging Face Company is a family owned and operated business. We pride ourselves on being the best
+in the business and our customer service is second to none.\n\nIf you have any questions about our
+products or services, feel free to contact us at any time. We look forward to hearing from you!']
+```
+
+### 다항 샘플링(Multinomial sampling)[[multinomial-sampling]]
+
+탐욕 탐색(greedy search)이 항상 가장 높은 확률을 가진 토큰을 다음 토큰으로 선택하는 것과 달리, 다항 샘플링(multinomial sampling, 조상 샘플링(ancestral sampling)이라고도 함)은 모델이 제공하는 전체 어휘에 대한 확률 분포를 기반으로 다음 토큰을 무작위로 선택합니다. 0이 아닌 확률을 가진 모든 토큰은 선택될 기회가 있으므로, 반복의 위험을 줄일 수 있습니다.
+
+다항 샘플링을 활성화하려면 `do_sample=True` 및 `num_beams=1`을 설정하세요.
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForCausalLM, set_seed
+>>> set_seed(0) # 재현성을 위해
+
+>>> checkpoint = "openai-community/gpt2-large"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+
+>>> prompt = "Today was an amazing day because"
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> outputs = model.generate(**inputs, do_sample=True, num_beams=1, max_new_tokens=100)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Today was an amazing day because when you go to the World Cup and you don\'t, or when you don\'t get invited,
+that\'s a terrible feeling."']
+```
+
+### 빔 탐색(Beam-search) 디코딩[[beam-search-decoding]]
+
+탐욕 검색(greedy search)과 달리, 빔 탐색(beam search) 디코딩은 각 시간 단계에서 여러 가설을 유지하고 결국 전체 시퀀스에 대해 가장 높은 확률을 가진 가설을 선택합니다. 이는 낮은 확률의 초기 토큰으로 시작하고 그리디 검색에서 무시되었을 가능성이 높은 시퀀스를 식별하는 이점이 있습니다.
+
+이 디코딩 전략을 활성화하려면 `num_beams` (추적할 가설 수라고도 함)를 1보다 크게 지정하세요.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> prompt = "It is astonishing how one can"
+>>> checkpoint = "openai-community/gpt2-medium"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+
+>>> outputs = model.generate(**inputs, num_beams=5, max_new_tokens=50)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['It is astonishing how one can have such a profound impact on the lives of so many people in such a short period of
+time."\n\nHe added: "I am very proud of the work I have been able to do in the last few years.\n\n"I have']
+```
+
+### 빔 탐색 다항 샘플링(Beam-search multinomial sampling)[[beam-search-multinomial-sampling]]
+
+이 디코딩 전략은 이름에서 알 수 있듯이 빔 탐색과 다항 샘플링을 결합한 것입니다. 이 디코딩 전략을 사용하기 위해서는 `num_beams`를 1보다 큰 값으로 설정하고, `do_sample=True`로 설정해야 합니다.
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM, set_seed
+>>> set_seed(0) # 재현성을 위해
+
+>>> prompt = "translate English to German: The house is wonderful."
+>>> checkpoint = "google-t5/t5-small"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+
+>>> outputs = model.generate(**inputs, num_beams=5, do_sample=True)
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'Das Haus ist wunderbar.'
+```
+
+### 다양한 빔 탐색 디코딩(Diverse beam search decoding)[[diverse-beam-search-decoding]]
+
+다양한 빔 탐색(Decoding) 전략은 선택할 수 있는 더 다양한 빔 시퀀스 집합을 생성할 수 있게 해주는 빔 탐색 전략의 확장입니다. 이 방법은 어떻게 작동하는지 알아보려면, [다양한 빔 탐색: 신경 시퀀스 모델에서 다양한 솔루션 디코딩하기](https://arxiv.org/pdf/1610.02424.pdf)를 참조하세요. 이 접근 방식은 세 가지 주요 매개변수를 가지고 있습니다: `num_beams`, `num_beam_groups`, 그리고 `diversity_penalty`. 다양성 패널티는 그룹 간에 출력이 서로 다르게 하기 위한 것이며, 각 그룹 내에서 빔 탐색이 사용됩니다.
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+>>> checkpoint = "google/pegasus-xsum"
+>>> prompt = (
+... "The Permaculture Design Principles are a set of universal design principles "
+... "that can be applied to any location, climate and culture, and they allow us to design "
+... "the most efficient and sustainable human habitation and food production systems. "
+... "Permaculture is a design system that encompasses a wide variety of disciplines, such "
+... "as ecology, landscape design, environmental science and energy conservation, and the "
+... "Permaculture design principles are drawn from these various disciplines. Each individual "
+... "design principle itself embodies a complete conceptual framework based on sound "
+... "scientific principles. When we bring all these separate principles together, we can "
+... "create a design system that both looks at whole systems, the parts that these systems "
+... "consist of, and how those parts interact with each other to create a complex, dynamic, "
+... "living system. Each design principle serves as a tool that allows us to integrate all "
+... "the separate parts of a design, referred to as elements, into a functional, synergistic, "
+... "whole system, where the elements harmoniously interact and work together in the most "
+... "efficient way possible."
+... )
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+
+>>> outputs = model.generate(**inputs, num_beams=5, num_beam_groups=5, max_new_tokens=30, diversity_penalty=1.0)
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'The Design Principles are a set of universal design principles that can be applied to any location, climate and
+culture, and they allow us to design the'
+```
+
+이 가이드에서는 다양한 디코딩 전략을 가능하게 하는 주요 매개변수를 보여줍니다. [`generate`] 메서드에 대한 고급 매개변수가 존재하므로 [`generate`] 메서드의 동작을 더욱 세부적으로 제어할 수 있습니다. 사용 가능한 매개변수의 전체 목록은 [API 문서](./main_classes/text_generation.md)를 참조하세요.
+
+### 추론 디코딩(Speculative Decoding)[[speculative-decoding]]
+
+추론 디코딩(보조 디코딩(assisted decoding)으로도 알려짐)은 동일한 토크나이저를 사용하는 훨씬 작은 보조 모델을 활용하여 몇 가지 후보 토큰을 생성하는 상위 모델의 디코딩 전략을 수정한 것입니다. 주 모델은 단일 전방 통과로 후보 토큰을 검증함으로써 디코딩 과정을 가속화합니다. `do_sample=True`일 경우, [추론 디코딩 논문](https://arxiv.org/pdf/2211.17192.pdf)에 소개된 토큰 검증과 재샘플링 방식이 사용됩니다.
+
+현재, 탐욕 검색(greedy search)과 샘플링만이 지원되는 보조 디코딩(assisted decoding) 기능을 통해, 보조 디코딩은 배치 입력을 지원하지 않습니다. 보조 디코딩에 대해 더 알고 싶다면, [이 블로그 포스트](https://huggingface.co/blog/assisted-generation)를 확인해 주세요.
+
+보조 디코딩을 활성화하려면 모델과 함께 `assistant_model` 인수를 설정하세요.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> prompt = "Alice and Bob"
+>>> checkpoint = "EleutherAI/pythia-1.4b-deduped"
+>>> assistant_checkpoint = "EleutherAI/pythia-160m-deduped"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+>>> assistant_model = AutoModelForCausalLM.from_pretrained(assistant_checkpoint)
+>>> outputs = model.generate(**inputs, assistant_model=assistant_model)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Alice and Bob are sitting in a bar. Alice is drinking a beer and Bob is drinking a']
+```
+
+샘플링 방법과 함께 보조 디코딩을 사용하는 경우 다항 샘플링과 마찬가지로 `temperature` 인수를 사용하여 무작위성을 제어할 수 있습니다. 그러나 보조 디코딩에서는 `temperature`를 낮추면 대기 시간을 개선하는 데 도움이 될 수 있습니다.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, set_seed
+>>> set_seed(42) # 재현성을 위해
+
+>>> prompt = "Alice and Bob"
+>>> checkpoint = "EleutherAI/pythia-1.4b-deduped"
+>>> assistant_checkpoint = "EleutherAI/pythia-160m-deduped"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+>>> inputs = tokenizer(prompt, return_tensors="pt")
+
+>>> model = AutoModelForCausalLM.from_pretrained(checkpoint)
+>>> assistant_model = AutoModelForCausalLM.from_pretrained(assistant_checkpoint)
+>>> outputs = model.generate(**inputs, assistant_model=assistant_model, do_sample=True, temperature=0.5)
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Alice and Bob, who were both in their early twenties, were both in the process of']
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/gguf.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/gguf.md
new file mode 100644
index 0000000000000000000000000000000000000000..03bd7c08bb2691c5214999cbe00d9e3cdacadfe2
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/gguf.md
@@ -0,0 +1,100 @@
+
+
+# GGUF와 Transformers의 상호작용 [[gguf-and-interaction-with-transformers]]
+
+GGUF 파일 형식은 [GGML](https://github.com/ggerganov/ggml)과 그에 의존하는 다른 라이브러리, 예를 들어 매우 인기 있는 [llama.cpp](https://github.com/ggerganov/llama.cpp)이나 [whisper.cpp](https://github.com/ggerganov/whisper.cpp)에서 추론을 위한 모델을 저장하는데 사용됩니다.
+
+이 파일 형식은 [Hugging Face Hub](https://huggingface.co/docs/hub/en/gguf)에서 지원되며, 파일 내의 텐서와 메타데이터를 신속하게 검사할 수 있는 기능을 제공합니다.
+
+이 형식은 "단일 파일 형식(single-file-format)"으로 설계되었으며, 하나의 파일에 설정 속성, 토크나이저 어휘, 기타 속성뿐만 아니라 모델에서 로드되는 모든 텐서가 포함됩니다. 이 파일들은 파일의 양자화 유형에 따라 다른 형식으로 제공됩니다. 다양한 양자화 유형에 대한 간략한 설명은 [여기](https://huggingface.co/docs/hub/en/gguf#quantization-types)에서 확인할 수 있습니다.
+
+## Transformers 내 지원 [[support-within-transformers]]
+
+`transformers` 내에서 `gguf` 파일을 로드할 수 있는 기능을 추가하여 GGUF 모델의 추가 학습/미세 조정을 제공한 후 `ggml` 생태계에서 다시 사용할 수 있도록 `gguf` 파일로 변환하는 기능을 제공합니다. 모델을 로드할 때 먼저 FP32로 역양자화한 후, PyTorch에서 사용할 수 있도록 가중치를 로드합니다.
+
+> [!NOTE]
+> 지원은 아직 초기 단계에 있으며, 다양한 양자화 유형과 모델 아키텍처에 대해 이를 강화하기 위한 기여를 환영합니다.
+
+현재 지원되는 모델 아키텍처와 양자화 유형은 다음과 같습니다:
+
+### 지원되는 양자화 유형 [[supported-quantization-types]]
+
+초기에 지원되는 양자화 유형은 Hub에서 공유된 인기 있는 양자화 파일에 따라 결정되었습니다.
+
+- F32
+- F16
+- BF16
+- Q4_0
+- Q4_1
+- Q5_0
+- Q5_1
+- Q8_0
+- Q2_K
+- Q3_K
+- Q4_K
+- Q5_K
+- Q6_K
+- IQ1_S
+- IQ1_M
+- IQ2_XXS
+- IQ2_XS
+- IQ2_S
+- IQ3_XXS
+- IQ3_S
+- IQ4_XS
+- IQ4_NL
+
+> [!NOTE]
+> GGUF 역양자화를 지원하려면 `gguf>=0.10.0` 설치가 필요합니다.
+
+### 지원되는 모델 아키텍처 [[supported-model-architectures]]
+
+현재 지원되는 모델 아키텍처는 Hub에서 매우 인기가 많은 아키텍처들로 제한되어 있습니다:
+
+- LLaMa
+- Mistral
+- Qwen2
+- Qwen2Moe
+- Phi3
+- Bloom
+
+## 사용 예시 [[example-usage]]
+
+`transformers`에서 `gguf` 파일을 로드하려면 `from_pretrained` 메소드에 `gguf_file` 인수를 지정해야 합니다. 동일한 파일에서 토크나이저와 모델을 로드하는 방법은 다음과 같습니다:
+
+```python
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+model_id = "TheBloke/TinyLlama-1.1B-Chat-v1.0-GGUF"
+filename = "tinyllama-1.1b-chat-v1.0.Q6_K.gguf"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id, gguf_file=filename)
+model = AutoModelForCausalLM.from_pretrained(model_id, gguf_file=filename)
+```
+
+이제 PyTorch 생태계에서 모델의 양자화되지 않은 전체 버전에 접근할 수 있으며, 다른 여러 도구들과 결합하여 사용할 수 있습니다.
+
+`gguf` 파일로 다시 변환하려면 llama.cpp의 [`convert-hf-to-gguf.py`](https://github.com/ggerganov/llama.cpp/blob/master/convert-hf-to-gguf.py)를 사용하는 것을 권장합니다.
+
+위의 스크립트를 완료하여 모델을 저장하고 다시 `gguf`로 내보내는 방법은 다음과 같습니다:
+
+```python
+tokenizer.save_pretrained('directory')
+model.save_pretrained('directory')
+
+!python ${path_to_llama_cpp}/convert-hf-to-gguf.py ${directory}
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/hpo_train.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/hpo_train.md
new file mode 100644
index 0000000000000000000000000000000000000000..c0982db5e093b55b750b655ea6e694c0f62826a8
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/hpo_train.md
@@ -0,0 +1,124 @@
+
+
+# Trainer API를 사용한 하이퍼파라미터 탐색 [[hyperparameter-search-using-trainer-api]]
+
+🤗 Transformers에서는 🤗 Transformers 모델을 학습시키는데 최적화된 [`Trainer`] 클래스를 제공하기 때문에, 사용자는 직접 훈련 루프를 작성할 필요 없이 더욱 간편하게 학습을 시킬 수 있습니다. 또한, [`Trainer`]는 하이퍼파라미터 탐색을 위한 API를 제공합니다. 이 문서에서 이 API를 활용하는 방법을 예시와 함께 보여드리겠습니다.
+
+## 하이퍼파라미터 탐색 백엔드 [[hyperparameter-search-backend]]
+
+[`Trainer`]는 현재 아래 4가지 하이퍼파라미터 탐색 백엔드를 지원합니다:
+[optuna](https://optuna.org/)와 [sigopt](https://sigopt.com/), [raytune](https://docs.ray.io/en/latest/tune/index.html), [wandb](https://wandb.ai/site/sweeps) 입니다.
+
+하이퍼파라미터 탐색 백엔드로 사용하기 전에 아래의 명령어를 사용하여 라이브러리들을 설치하세요.
+```bash
+pip install optuna/sigopt/wandb/ray[tune]
+```
+
+## 예제에서 하이퍼파라미터 탐색을 활성화하는 방법 [[how-to-enable-hyperparameter-search-in-example]]
+
+하이퍼파라미터 탐색 공간을 정의하세요. 하이퍼파라미터 탐색 백엔드마다 서로 다른 형식이 필요합니다.
+
+sigopt의 경우, 해당 [object_parameter](https://docs.sigopt.com/ai-module-api-references/api_reference/objects/object_parameter) 문서를 참조하여 아래와 같이 작성하세요:
+```py
+>>> def sigopt_hp_space(trial):
+... return [
+... {"bounds": {"min": 1e-6, "max": 1e-4}, "name": "learning_rate", "type": "double"},
+... {
+... "categorical_values": ["16", "32", "64", "128"],
+... "name": "per_device_train_batch_size",
+... "type": "categorical",
+... },
+... ]
+```
+
+optuna의 경우, 해당 [object_parameter](https://optuna.readthedocs.io/en/stable/tutorial/10_key_features/002_configurations.html#sphx-glr-tutorial-10-key-features-002-configurations-py) 문서를 참조하여 아래와 같이 작성하세요:
+
+```py
+>>> def optuna_hp_space(trial):
+... return {
+... "learning_rate": trial.suggest_float("learning_rate", 1e-6, 1e-4, log=True),
+... "per_device_train_batch_size": trial.suggest_categorical("per_device_train_batch_size", [16, 32, 64, 128]),
+... }
+```
+
+raytune의 경우, 해당 [object_parameter](https://docs.ray.io/en/latest/tune/api/search_space.html) 문서를 참조하여 아래와 같이 작성하세요:
+
+```py
+>>> def ray_hp_space(trial):
+... return {
+... "learning_rate": tune.loguniform(1e-6, 1e-4),
+... "per_device_train_batch_size": tune.choice([16, 32, 64, 128]),
+... }
+```
+
+wandb의 경우, 해당 [object_parameter](https://docs.wandb.ai/guides/sweeps/configuration) 문서를 참조하여 아래와 같이 작성하세요:
+
+```py
+>>> def wandb_hp_space(trial):
+... return {
+... "method": "random",
+... "metric": {"name": "objective", "goal": "minimize"},
+... "parameters": {
+... "learning_rate": {"distribution": "uniform", "min": 1e-6, "max": 1e-4},
+... "per_device_train_batch_size": {"values": [16, 32, 64, 128]},
+... },
+... }
+```
+
+`model_init` 함수를 정의하고 이를 [`Trainer`]에 전달하세요. 아래는 그 예시입니다.
+```py
+>>> def model_init(trial):
+... return AutoModelForSequenceClassification.from_pretrained(
+... model_args.model_name_or_path,
+... from_tf=bool(".ckpt" in model_args.model_name_or_path),
+... config=config,
+... cache_dir=model_args.cache_dir,
+... revision=model_args.model_revision,
+... token=True if model_args.use_auth_token else None,
+... )
+```
+
+아래와 같이 `model_init` 함수, 훈련 인수, 훈련 및 테스트 데이터셋, 그리고 평가 함수를 사용하여 [`Trainer`]를 생성하세요:
+
+```py
+>>> trainer = Trainer(
+... model=None,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... processing_class=tokenizer,
+... model_init=model_init,
+... data_collator=data_collator,
+... )
+```
+
+하이퍼파라미터 탐색을 호출하고, 최적의 시험 매개변수를 가져오세요. 백엔드는 `"optuna"`/`"sigopt"`/`"wandb"`/`"ray"` 중에서 선택할 수 있습니다. 방향은 `"minimize"` 또는 `"maximize"` 중 선택하며, 목표를 최소화할 것인지 최대화할 것인지를 결정합니다.
+
+자신만의 compute_objective 함수를 정의할 수 있습니다. 만약 이 함수를 정의하지 않으면, 기본 compute_objective가 호출되고, f1과 같은 평가 지표의 합이 목푯값으로 반환됩니다.
+
+```py
+>>> best_trial = trainer.hyperparameter_search(
+... direction="maximize",
+... backend="optuna",
+... hp_space=optuna_hp_space,
+... n_trials=20,
+... compute_objective=compute_objective,
+... )
+```
+
+## DDP 미세 조정을 위한 하이퍼파라미터 탐색 [[hyperparameter-search-for-ddp-finetune]]
+현재, DDP(Distributed Data Parallelism; 분산 데이터 병렬처리)를 위한 하이퍼파라미터 탐색은 optuna와 sigopt에서 가능합니다. 최상위 프로세스가 하이퍼파라미터 탐색 과정을 시작하고 그 결과를 다른 프로세스에 전달합니다.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/in_translation.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/in_translation.md
new file mode 100644
index 0000000000000000000000000000000000000000..61ff1426a4522a90b54a33e3b0c91d8a9a1f4d7c
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/in_translation.md
@@ -0,0 +1,5 @@
+
+
+# 열심히 번역 중입니다. 조금 이따 만나요!
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/index.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/index.md
new file mode 100644
index 0000000000000000000000000000000000000000..0726085c5b3ae781f77881a9cbb176db5841bfdc
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/index.md
@@ -0,0 +1,362 @@
+
+
+# 🤗 Transformers
+
+[PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/), [JAX](https://jax.readthedocs.io/en/latest/)를 위한 최첨단 머신러닝
+
+🤗 Transformers는 사전학습된 최첨단 모델들을 쉽게 다운로드하고 훈련시킬 수 있는 API와 도구를 제공합니다. 사전학습된 모델을 쓰면 컴퓨팅 비용과 탄소 배출량이 줄고, 모델을 처음부터 훈련시키는 데 필요한 시간과 리소스를 절약할 수 있습니다. 저희 모델들은 다양한 분야의 태스크를 지원합니다.
+
+📝 **자연어 처리**: 텍스트 분류, 개체명 인식, 질의응답, 언어 모델링, 요약, 번역, 객관식 질의응답, 텍스트 생성
+🖼️ **컴퓨터 비전**: 이미지 분류, 객체 탐지, 객체 분할
+🗣️ **오디오**: 자동음성인식, 오디오 분류
+🐙 **멀티모달**: 표 질의응답, 광학 문자 인식 (OCR), 스캔한 문서에서 정보 추출, 비디오 분류, 시각 질의응답
+
+🤗 Transformers는 PyTorch, TensorFlow와 JAX 간의 상호운용성을 지원합니다. 유연하게 모델의 각 단계마다 다른 프레임워크를 사용할 수도 있습니다. 예를 들어 코드 3줄만 써서 모델을 훈련시킨 다음, 다른 프레임워크 상에서 추론할 수 있습니다. 모델을 운영 환경에 배포하기 위해 ONNX나 TorchScript 형식으로 내보낼 수도 있습니다.
+
+커뮤니티에 참여하시려면 [Hub](https://huggingface.co/models), [포럼](https://discuss.huggingface.co/), [디스코드](https://discord.com/invite/JfAtkvEtRb)를 방문해주세요!
+
+## Hugging Face 팀과 직접 대화하고 싶으신가요?[[hugging-face-team]]
+
+
+
+
+
+## 콘텐츠[[contents]]
+
+저희 기술문서는 크게 5개 섹션으로 나눌 수 있습니다:
+
+- **시작하기**에서 라이브러리를 간단히 훑어보고, 본격적으로 뛰어들 수 있게 설치 방법을 안내합니다.
+- **튜토리얼**에서 라이브러리에 익숙해질 수 있도록 자세하고도 쉽게 기본적인 부분을 안내합니다.
+- **How-to 가이드**에서 언어 모델링을 위해 사전학습된 모델을 파인 튜닝하는 방법이나, 직접 모델을 작성하고 공유하는 방법과 같이 특정 목표를 달성하는 방법을 안내합니다.
+- **개념 가이드**에서 🤗 Transformers의 설계 철학과 함께 모델이나 태스크 뒤에 숨겨진 개념들과 아이디어를 탐구하고 설명을 덧붙입니다.
+- **API**에서 모든 클래스와 함수를 설명합니다.
+
+ - **메인 클래스**에서 configuration, model, tokenizer, pipeline과 같이 제일 중요한 클래스들을 자세히 설명합니다.
+ - **모델**에서 라이브러리 속 구현된 각 모델과 연관된 클래스와 함수를 자세히 설명합니다.
+ - **내부 유틸리티**에서 내부적으로 사용되는 유틸리티 클래스와 함수를 자세히 설명합니다.
+
+### 지원 모델[[supported-models]]
+
+
+
+1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
+1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
+1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
+1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
+1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
+1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
+1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
+1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BLOOM](model_doc/bloom)** (from BigScience workshop) released by the [BigScience Workshop](https://bigscience.huggingface.co/).
+1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499) by Adrian de Wynter and Daniel J. Perry.
+1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
+1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
+1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
+1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
+1. **[CLIPSeg](model_doc/clipseg)** (from University of Göttingen) released with the paper [Image Segmentation Using Text and Image Prompts](https://arxiv.org/abs/2112.10003) by Timo Lüddecke and Alexander Ecker.
+1. **[CodeGen](model_doc/codegen)** (from Salesforce) released with the paper [A Conversational Paradigm for Program Synthesis](https://arxiv.org/abs/2203.13474) by Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Savarese, Caiming Xiong.
+1. **[Conditional DETR](model_doc/conditional_detr)** (from Microsoft Research Asia) released with the paper [Conditional DETR for Fast Training Convergence](https://arxiv.org/abs/2108.06152) by Depu Meng, Xiaokang Chen, Zejia Fan, Gang Zeng, Houqiang Li, Yuhui Yuan, Lei Sun, Jingdong Wang.
+1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
+1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
+1. **[CvT](model_doc/cvt)** (from Microsoft) released with the paper [CvT: Introducing Convolutions to Vision Transformers](https://arxiv.org/abs/2103.15808) by Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang.
+1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
+1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+1. **[Deformable DETR](model_doc/deformable_detr)** (from SenseTime Research) released with the paper [Deformable DETR: Deformable Transformers for End-to-End Object Detection](https://arxiv.org/abs/2010.04159) by Xizhou Zhu, Weijie Su, Lewei Lu, Bin Li, Xiaogang Wang, Jifeng Dai.
+1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
+1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
+1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
+1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) and a German version of DistilBERT.
+1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
+1. **[Donut](model_doc/donut)** (from NAVER), released together with the paper [OCR-free Document Understanding Transformer](https://arxiv.org/abs/2111.15664) by Geewook Kim, Teakgyu Hong, Moonbin Yim, Jeongyeon Nam, Jinyoung Park, Jinyeong Yim, Wonseok Hwang, Sangdoo Yun, Dongyoon Han, Seunghyun Park.
+1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
+1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+1. **[EfficientNet](model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://arxiv.org/abs/1905.11946) by Mingxing Tan and Quoc V. Le.
+1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
+1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[ERNIE](model_doc/ernie)** (from Baidu) released with the paper [ERNIE: Enhanced Representation through Knowledge Integration](https://arxiv.org/abs/1904.09223) by Yu Sun, Shuohuan Wang, Yukun Li, Shikun Feng, Xuyi Chen, Han Zhang, Xin Tian, Danxiang Zhu, Hao Tian, Hua Wu.
+1. **[ESM](model_doc/esm)** (from Meta AI) are transformer protein language models. **ESM-1b** was released with the paper [Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118) by Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott, C. Lawrence Zitnick, Jerry Ma, and Rob Fergus. **ESM-1v** was released with the paper [Language models enable zero-shot prediction of the effects of mutations on protein function](https://doi.org/10.1101/2021.07.09.450648) by Joshua Meier, Roshan Rao, Robert Verkuil, Jason Liu, Tom Sercu and Alexander Rives. **ESM-2 and ESMFold** were released with the paper [Language models of protein sequences at the scale of evolution enable accurate structure prediction](https://doi.org/10.1101/2022.07.20.500902) by Zeming Lin, Halil Akin, Roshan Rao, Brian Hie, Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido, Alexander Rives.
+1. **[FLAN-T5](model_doc/flan-t5)** (from Google AI) released in the repository [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-t5-checkpoints) by Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V. Le, and Jason Wei
+1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
+1. **[FLAVA](model_doc/flava)** (from Facebook AI) released with the paper [FLAVA: A Foundational Language And Vision Alignment Model](https://arxiv.org/abs/2112.04482) by Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela.
+1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
+1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
+1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
+1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
+1. **[GPT NeoX](model_doc/gpt_neox)** (from EleutherAI) released with the paper [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://arxiv.org/abs/2204.06745) by Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach
+1. **[GPT NeoX Japanese](model_doc/gpt_neox_japanese)** (from ABEJA) released by Shinya Otani, Takayoshi Makabe, Anuj Arora, and Kyo Hattori.
+1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
+1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
+1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released in the repository [tanreinama/GPTSAN](https://github.com/tanreinama/GPTSAN/blob/main/report/model.md) by Toshiyuki Sakamoto(tanreinama).
+1. **[GroupViT](model_doc/groupvit)** (from UCSD, NVIDIA) released with the paper [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://arxiv.org/abs/2202.11094) by Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang.
+1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
+1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
+1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
+1. **[Jukebox](model_doc/jukebox)** (from OpenAI) released with the paper [Jukebox: A Generative Model for Music](https://arxiv.org/pdf/2005.00341.pdf) by Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford, Ilya Sutskever.
+1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
+1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
+1. **[LayoutLMv3](model_doc/layoutlmv3)** (from Microsoft Research Asia) released with the paper [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://arxiv.org/abs/2204.08387) by Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
+1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
+1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LeViT](model_doc/levit)** (from Meta AI) released with the paper [LeViT: A Vision Transformer in ConvNet's Clothing for Faster Inference](https://arxiv.org/abs/2104.01136) by Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze.
+1. **[LiLT](model_doc/lilt)** (from South China University of Technology) released with the paper [LiLT: A Simple yet Effective Language-Independent Layout Transformer for Structured Document Understanding](https://arxiv.org/abs/2202.13669) by Jiapeng Wang, Lianwen Jin, Kai Ding.
+1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LongT5](model_doc/longt5)** (from Google AI) released with the paper [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://arxiv.org/abs/2112.07916) by Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung, Yinfei Yang.
+1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
+1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490) by Hao Tan and Mohit Bansal.
+1. **[M-CTC-T](model_doc/mctct)** (from Facebook) released with the paper [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://arxiv.org/abs/2111.00161) by Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert.
+1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
+1. **[MarkupLM](model_doc/markuplm)** (from Microsoft Research Asia) released with the paper [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document Understanding](https://arxiv.org/abs/2110.08518) by Junlong Li, Yiheng Xu, Lei Cui, Furu Wei.
+1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
+1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
+1. **[mBART](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+1. **[mBART-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
+1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
+1. **[MobileBERT](model_doc/mobilebert)** (from CMU/Google Brain) released with the paper [MobileBERT: a Compact Task-Agnostic BERT for Resource-Limited Devices](https://arxiv.org/abs/2004.02984) by Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny Zhou.
+1. **[MobileViT](model_doc/mobilevit)** (from Apple) released with the paper [MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer](https://arxiv.org/abs/2110.02178) by Sachin Mehta and Mohammad Rastegari.
+1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
+1. **[MVP](model_doc/mvp)** (from RUC AI Box) released with the paper [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://arxiv.org/abs/2206.12131) by Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen.
+1. **[Nezha](model_doc/nezha)** (from Huawei Noah’s Ark Lab) released with the paper [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://arxiv.org/abs/1909.00204) by Junqiu Wei, Xiaozhe Ren, Xiaoguang Li, Wenyong Huang, Yi Liao, Yasheng Wang, Jiashu Lin, Xin Jiang, Xiao Chen and Qun Liu.
+1. **[NLLB](model_doc/nllb)** (from Meta) released with the paper [No Language Left Behind: Scaling Human-Centered Machine Translation](https://arxiv.org/abs/2207.04672) by the NLLB team.
+1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
+1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
+1. **[OPT](master/model_doc/opt)** (from Meta AI) released with the paper [OPT: Open Pre-trained Transformer Language Models](https://arxiv.org/abs/2205.01068) by Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al.
+1. **[OWL-ViT](model_doc/owlvit)** (from Google AI) released with the paper [Simple Open-Vocabulary Object Detection with Vision Transformers](https://arxiv.org/abs/2205.06230) by Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby.
+1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
+1. **[PEGASUS-X](model_doc/pegasus_x)** (from Google) released with the paper [Investigating Efficiently Extending Transformers for Long Input Summarization](https://arxiv.org/abs/2208.04347) by Jason Phang, Yao Zhao, and Peter J. Liu.
+1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
+1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
+1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
+1. **[RAG](model_doc/rag)** (from Facebook) released with the paper [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://arxiv.org/abs/2005.11401) by Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela.
+1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
+1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://arxiv.org/abs/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
+1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
+1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
+1. **[RoCBert](model_doc/roc_bert)** (from WeChatAI) released with the paper [RoCBert: Robust Chinese Bert with Multimodal Contrastive Pretraining](https://aclanthology.org/2022.acl-long.65.pdf) by HuiSu, WeiweiShi, XiaoyuShen, XiaoZhou, TuoJi, JiaruiFang, JieZhou.
+1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
+1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
+1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
+1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
+1. **[SqueezeBERT](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
+1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+1. **[Swin Transformer V2](model_doc/swinv2)** (from Microsoft) released with the paper [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883) by Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo.
+1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[Table Transformer](model_doc/table-transformer)** (from Microsoft Research) released with the paper [PubTables-1M: Towards Comprehensive Table Extraction From Unstructured Documents](https://arxiv.org/abs/2110.00061) by Brandon Smock, Rohith Pesala, Robin Abraham.
+1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
+1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
+1. **[Time Series Transformer](model_doc/time_series_transformer)** (from HuggingFace).
+1. **[Trajectory Transformer](model_doc/trajectory_transformers)** (from the University of California at Berkeley) released with the paper [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://arxiv.org/abs/2106.02039) by Michael Janner, Qiyang Li, Sergey Levine
+1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
+1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
+1. **[UL2](model_doc/ul2)** (from Google Research) released with the paper [Unifying Language Learning Paradigms](https://arxiv.org/abs/2205.05131v1) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler
+1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
+1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
+1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://arxiv.org/abs/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+1. **[VideoMAE](model_doc/videomae)** (from Multimedia Computing Group, Nanjing University) released with the paper [VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training](https://arxiv.org/abs/2203.12602) by Zhan Tong, Yibing Song, Jue Wang, Limin Wang.
+1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
+1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
+1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
+1. **[ViTMSN](model_doc/vit_msn)** (from Meta AI) released with the paper [Masked Siamese Networks for Label-Efficient Learning](https://arxiv.org/abs/2204.07141) by Mahmoud Assran, Mathilde Caron, Ishan Misra, Piotr Bojanowski, Florian Bordes, Pascal Vincent, Armand Joulin, Michael Rabbat, Nicolas Ballas.
+1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
+1. **[Wav2Vec2-Conformer](model_doc/wav2vec2-conformer)** (from Facebook AI) released with the paper [FAIRSEQ S2T: Fast Speech-to-Text Modeling with FAIRSEQ](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Sravya Popuri, Dmytro Okhonko, Juan Pino.
+1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
+1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
+1. **[Whisper](model_doc/whisper)** (from OpenAI) released with the paper [Robust Speech Recognition via Large-Scale Weak Supervision](https://cdn.openai.com/papers/whisper.pdf) by Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever.
+1. **[X-CLIP](model_doc/xclip)** (from Microsoft Research) released with the paper [Expanding Language-Image Pretrained Models for General Video Recognition](https://arxiv.org/abs/2208.02816) by Bolin Ni, Houwen Peng, Minghao Chen, Songyang Zhang, Gaofeng Meng, Jianlong Fu, Shiming Xiang, Haibin Ling.
+1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
+1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291) by Guillaume Lample and Alexis Conneau.
+1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
+1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
+1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
+1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
+1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
+1. **[YOLOS](model_doc/yolos)** (from Huazhong University of Science & Technology) released with the paper [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://arxiv.org/abs/2106.00666) by Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu.
+1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
+
+
+### 지원 프레임워크[[supported-framework]]
+
+아래 표는 라이브러리 속 각 모델의 지원 현황을 나타냅니다. 토큰화를 파이썬 (별칭 "slow") 또는 🤗 Tokenizers (별칭 "fast") 라이브러리로 하는지; (Flax를 통한) Jax, PyTorch, TensorFlow 중 어떤 프레임워크를 지원하는지 표시되어 있습니다.
+
+
+
+| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:---------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBird-Pegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BLOOM | ❌ | ✅ | ✅ | ❌ | ❌ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| CANINE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CLIPSeg | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CodeGen | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Conditional DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNeXT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| CvT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Deformable DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DonutSwin | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ERNIE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ESM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FLAVA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
+| GPT NeoX Japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| GroupViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Jukebox | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LayoutLMv3 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LeViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LiLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LongT5 | ❌ | ❌ | ✅ | ❌ | ✅ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M-CTC-T | ❌ | ❌ | ✅ | ❌ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MarkupLM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Megatron-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MobileViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MVP | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Nezha | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Nyströmformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| OPT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| OWL-ViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| PEGASUS-X | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| REALM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoCBert | ✅ | ❌ | ✅ | ❌ | ❌ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| SegFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Swin Transformer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Swin Transformer V2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Table Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Time Series Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VideoMAE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| VisualBERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| ViTMSN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Whisper | ✅ | ❌ | ✅ | ✅ | ❌ |
+| X-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/installation.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/installation.md
new file mode 100644
index 0000000000000000000000000000000000000000..a744db40d291236a10b6b93c06d99c0b31a0a33d
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/installation.md
@@ -0,0 +1,245 @@
+
+
+# 설치방법[[installation]]
+
+🤗 Transformers를 사용 중인 딥러닝 라이브러리에 맞춰 설치하고, 캐시를 구성하거나 선택적으로 오프라인에서도 실행할 수 있도록 🤗 Transformers를 설정하는 방법을 배우겠습니다.
+
+🤗 Transformers는 Python 3.6+, PyTorch 1.1.0+, TensorFlow 2.0+ 및 Flax에서 테스트되었습니다. 딥러닝 라이브러리를 설치하려면 아래 링크된 저마다의 공식 사이트를 참고해주세요.
+
+* [PyTorch](https://pytorch.org/get-started/locally/) 설치하기
+* [TensorFlow 2.0](https://www.tensorflow.org/install/pip) 설치하기
+* [Flax](https://flax.readthedocs.io/en/latest/) 설치하기
+
+## pip으로 설치하기[[install-with-pip]]
+
+🤗 Transformers를 [가상 환경](https://docs.python.org/3/library/venv.html)에 설치하는 것을 추천드립니다. Python 가상 환경에 익숙하지 않다면, 이 [가이드](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/)를 참고하세요. 가상 환경을 사용하면 서로 다른 프로젝트들을 보다 쉽게 관리할 수 있고, 의존성 간의 호환성 문제를 방지할 수 있습니다.
+
+먼저 프로젝트 디렉토리에서 가상 환경을 만들어 줍니다.
+
+```bash
+python -m venv .env
+```
+
+가상 환경을 활성화해주세요. Linux나 MacOS의 경우:
+
+```bash
+source .env/bin/activate
+```
+Windows의 경우:
+
+```bash
+.env/Scripts/activate
+```
+
+이제 🤗 Transformers를 설치할 준비가 되었습니다. 다음 명령을 입력해주세요.
+
+```bash
+pip install transformers
+```
+
+CPU만 써도 된다면, 🤗 Transformers와 딥러닝 라이브러리를 단 1줄로 설치할 수 있습니다. 예를 들어 🤗 Transformers와 PyTorch의 경우:
+
+```bash
+pip install transformers[torch]
+```
+
+🤗 Transformers와 TensorFlow 2.0의 경우:
+
+```bash
+pip install transformers[tf-cpu]
+```
+
+🤗 Transformers와 Flax의 경우:
+
+```bash
+pip install transformers[flax]
+```
+
+마지막으로 🤗 Transformers가 제대로 설치되었는지 확인할 차례입니다. 사전훈련된 모델을 다운로드하는 코드입니다.
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('we love you'))"
+```
+
+라벨과 점수가 출력되면 잘 설치된 것입니다.
+
+```bash
+[{'label': 'POSITIVE', 'score': 0.9998704791069031}]
+```
+
+## 소스에서 설치하기[[install-from-source]]
+
+🤗 Transformers를 소스에서 설치하려면 아래 명령을 실행하세요.
+
+```bash
+pip install git+https://github.com/huggingface/transformers
+```
+
+위 명령은 최신이지만 (안정적인) `stable` 버전이 아닌 실험성이 짙은 `main` 버전을 설치합니다. `main` 버전은 개발 현황과 발맞추는데 유용합니다. 예시로 마지막 공식 릴리스 이후 발견된 버그가 패치되었지만, 새 릴리스로 아직 롤아웃되지는 않은 경우를 들 수 있습니다. 바꿔 말하면 `main` 버전이 안정성과는 거리가 있다는 뜻이기도 합니다. 저희는 `main` 버전을 사용하는데 문제가 없도록 노력하고 있으며, 대부분의 문제는 대개 몇 시간이나 하루 안에 해결됩니다. 만약 문제가 발생하면 [이슈](https://github.com/huggingface/transformers/issues)를 열어주시면 더 빨리 해결할 수 있습니다!
+
+전과 마찬가지로 🤗 Transformers가 제대로 설치되었는지 확인할 차례입니다.
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('I love you'))"
+```
+
+## 수정 가능한 설치[[editable-install]]
+
+수정 가능한 설치가 필요한 경우는 다음과 같습니다.
+
+* `main` 버전의 소스 코드를 사용하기 위해
+* 🤗 Transformers에 기여하고 싶어서 코드의 변경 사항을 테스트하기 위해
+
+리포지터리를 복제하고 🤗 Transformers를 설치하려면 다음 명령을 입력해주세요.
+
+```bash
+git clone https://github.com/huggingface/transformers.git
+cd transformers
+pip install -e .
+```
+
+위 명령은 리포지터리를 복제한 위치의 폴더와 Python 라이브러리의 경로를 연결시킵니다. Python이 일반 라이브러리 경로 외에 복제한 폴더 내부를 확인할 것입니다. 예를 들어 Python 패키지가 일반적으로 `~/anaconda3/envs/main/lib/python3.7/site-packages/`에 설치되어 있는데, 명령을 받은 Python이 이제 복제한 폴더인 `~/transformers/`도 검색하게 됩니다.
+
+
+
+라이브러리를 계속 사용하려면 `transformers` 폴더를 꼭 유지해야 합니다.
+
+
+
+복제본은 최신 버전의 🤗 Transformers로 쉽게 업데이트할 수 있습니다.
+
+```bash
+cd ~/transformers/
+git pull
+```
+
+Python 환경을 다시 실행하면 업데이트된 🤗 Transformers의 `main` 버전을 찾아낼 것입니다.
+
+## conda로 설치하기[[install-with-conda]]
+
+`conda-forge` conda 채널에서 설치할 수 있습니다.
+
+```bash
+conda install conda-forge::transformers
+```
+
+## 캐시 구성하기[[cache-setup]]
+
+사전훈련된 모델은 다운로드된 후 로컬 경로 `~/.cache/huggingface/hub`에 캐시됩니다. 셸 환경 변수 `TRANSFORMERS_CACHE`의 기본 디렉터리입니다. Windows의 경우 기본 디렉터리는 `C:\Users\username\.cache\huggingface\hub`입니다. 아래의 셸 환경 변수를 (우선 순위) 순서대로 변경하여 다른 캐시 디렉토리를 지정할 수 있습니다.
+
+1. 셸 환경 변수 (기본): `HF_HUB_CACHE` 또는 `TRANSFORMERS_CACHE`
+2. 셸 환경 변수: `HF_HOME`
+3. 셸 환경 변수: `XDG_CACHE_HOME` + `/huggingface`
+
+
+
+과거 🤗 Transformers에서 쓰였던 셸 환경 변수 `PYTORCH_TRANSFORMERS_CACHE` 또는 `PYTORCH_PRETRAINED_BERT_CACHE`이 설정되있다면, 셸 환경 변수 `TRANSFORMERS_CACHE`을 지정하지 않는 한 우선 사용됩니다.
+
+
+
+## 오프라인 모드[[offline-mode]]
+
+🤗 Transformers를 로컬 파일만 사용하도록 해서 방화벽 또는 오프라인 환경에서 실행할 수 있습니다. 활성화하려면 `HF_HUB_OFFLINE=1` 환경 변수를 설정하세요.
+
+
+
+`HF_DATASETS_OFFLINE=1` 환경 변수를 설정하여 오프라인 훈련 과정에 [🤗 Datasets](https://huggingface.co/docs/datasets/)을 추가할 수 있습니다.
+
+
+
+예를 들어 외부 기기 사이에 방화벽을 둔 일반 네트워크에서 평소처럼 프로그램을 다음과 같이 실행할 수 있습니다.
+
+```bash
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+오프라인 기기에서 동일한 프로그램을 다음과 같이 실행할 수 있습니다.
+
+```bash
+HF_DATASETS_OFFLINE=1 HF_HUB_OFFLINE=1 \
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+이제 스크립트는 로컬 파일에 한해서만 검색할 것이므로, 스크립트가 중단되거나 시간이 초과될 때까지 멈춰있지 않고 잘 실행될 것입니다.
+
+### 오프라인용 모델 및 토크나이저 만들어두기[[fetch-models-and-tokenizers-to-use-offline]]
+
+Another option for using 🤗 Transformers offline is to download the files ahead of time, and then point to their local path when you need to use them offline. There are three ways to do this:
+🤗 Transformers를 오프라인으로 사용하는 또 다른 방법은 파일을 미리 다운로드한 다음, 오프라인일 때 사용할 로컬 경로를 지정해두는 것입니다. 3가지 중 편한 방법을 고르세요.
+
+* [Model Hub](https://huggingface.co/models)의 UI를 통해 파일을 다운로드하려면 ↓ 아이콘을 클릭하세요.
+
+ 
+
+* [`PreTrainedModel.from_pretrained`]와 [`PreTrainedModel.save_pretrained`] 워크플로를 활용하세요.
+
+ 1. 미리 [`PreTrainedModel.from_pretrained`]로 파일을 다운로드해두세요.
+
+ ```py
+ >>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("bigscience/T0_3B")
+ >>> model = AutoModelForSeq2SeqLM.from_pretrained("bigscience/T0_3B")
+ ```
+
+ 2. [`PreTrainedModel.save_pretrained`]로 지정된 경로에 파일을 저장해두세요.
+
+ ```py
+ >>> tokenizer.save_pretrained("./your/path/bigscience_t0")
+ >>> model.save_pretrained("./your/path/bigscience_t0")
+ ```
+
+ 3. 이제 오프라인일 때 [`PreTrainedModel.from_pretrained`]로 저장해뒀던 파일을 지정된 경로에서 다시 불러오세요.
+
+ ```py
+ >>> tokenizer = AutoTokenizer.from_pretrained("./your/path/bigscience_t0")
+ >>> model = AutoModel.from_pretrained("./your/path/bigscience_t0")
+ ```
+
+* [huggingface_hub](https://github.com/huggingface/huggingface_hub/tree/main/src/huggingface_hub) 라이브러리를 활용해서 파일을 다운로드하세요.
+
+ 1. 가상환경에 `huggingface_hub` 라이브러리를 설치하세요.
+
+ ```bash
+ python -m pip install huggingface_hub
+ ```
+
+ 2. [`hf_hub_download`](https://huggingface.co/docs/hub/adding-a-library#download-files-from-the-hub) 함수로 파일을 특정 위치에 다운로드할 수 있습니다. 예를 들어 아래 명령은 [T0](https://huggingface.co/bigscience/T0_3B) 모델의 `config.json` 파일을 지정된 경로에 다운로드합니다.
+
+ ```py
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> hf_hub_download(repo_id="bigscience/T0_3B", filename="config.json", cache_dir="./your/path/bigscience_t0")
+ ```
+
+파일을 다운로드하고 로컬에 캐시 해놓고 나면, 나중에 불러와 사용할 수 있도록 로컬 경로를 지정해두세요.
+
+```py
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("./your/path/bigscience_t0/config.json")
+```
+
+
+
+Hub에 저장된 파일을 다운로드하는 방법을 더 자세히 알아보려면 [Hub에서 파일 다운로드하기](https://huggingface.co/docs/hub/how-to-downstream) 섹션을 참고해주세요.
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/audio_utils.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/audio_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..811f7c0866bd509e0b22c53111330cdacd8c4320
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/audio_utils.md
@@ -0,0 +1,39 @@
+
+
+# `FeatureExtractors`를 위한 유틸리티 [[utilities-for-featureextractors]]
+
+이 페이지는 오디오 [`FeatureExtractor`]가 *단시간 푸리에 변환(Short Time Fourier Transform)* 또는 *로그 멜 스펙트로그램(log mel spectrogram)*과 같은 일반적인 알고리즘을 사용하여 원시 오디오에서 특수한 특성을 계산하는 데 사용할 수 있는 유틸리티 함수들을 나열합니다.
+
+이 함수들 대부분은 라이브러리 내 오디오 처리 코드를 연구할 때에만 유용합니다.
+
+## 오디오 변환 [[transformers.audio_utils.hertz_to_mel]]
+
+[[autodoc]] audio_utils.hertz_to_mel
+
+[[autodoc]] audio_utils.mel_to_hertz
+
+[[autodoc]] audio_utils.mel_filter_bank
+
+[[autodoc]] audio_utils.optimal_fft_length
+
+[[autodoc]] audio_utils.window_function
+
+[[autodoc]] audio_utils.spectrogram
+
+[[autodoc]] audio_utils.power_to_db
+
+[[autodoc]] audio_utils.amplitude_to_db
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/file_utils.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/file_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..7effad44baa170fba6b4bc8b954f57c2fd208323
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/file_utils.md
@@ -0,0 +1,50 @@
+
+
+# 일반 유틸리티 (General Utilities) [[general-utilities]]
+
+이 페이지는 `utils.py` 파일에 있는 Transformers의 일반 유틸리티 함수들을 나열합니다.
+
+이 함수들 대부분은 라이브러리의 일반적인 코드를 연구할 때만 유용합니다.
+
+
+## Enums 및 namedtuples [[transformers.utils.ExplicitEnum]]
+
+[[autodoc]] utils.ExplicitEnum
+
+[[autodoc]] utils.PaddingStrategy
+
+[[autodoc]] utils.TensorType
+
+## 특수 데코레이터 (Special Decorators) [[transformers.add_start_docstrings]]
+
+[[autodoc]] utils.add_start_docstrings
+
+[[autodoc]] utils.add_start_docstrings_to_model_forward
+
+[[autodoc]] utils.add_end_docstrings
+
+[[autodoc]] utils.add_code_sample_docstrings
+
+[[autodoc]] utils.replace_return_docstrings
+
+## 특수 속성 (Special Properties) [[transformers.utils.cached_property]]
+
+[[autodoc]] utils.cached_property
+
+## 기타 유틸리티 [[transformers.utils._LazyModule]]
+
+[[autodoc]] utils._LazyModule
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/generation_utils.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/generation_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..a66411f71e9ee8ebb8aa293fa540bda77eeb2d2f
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/generation_utils.md
@@ -0,0 +1,413 @@
+
+
+# 생성을 위한 유틸리티 [[utilities-for-generation]]
+
+이 페이지는 [`~generation.GenerationMixin.generate`]에서 사용되는 모든 유틸리티 함수들을 나열합니다.
+
+## 출력을 생성하기 (Generate Outputs) [[generate-outputs]]
+
+[`~generation.GenerationMixin.generate`]의 출력은 [`~utils.ModelOutput`]의 하위 클래스의 인스턴스입니다. 이 출력은 [`~generation.GenerationMixin.generate`]에서 반환되는 모든 정보를 포함하는 데이터 구조체이며, 튜플 또는 딕셔너리로도 사용할 수 있습니다.
+
+다음은 예시입니다:
+
+```python
+from transformers import GPT2Tokenizer, GPT2LMHeadModel
+
+tokenizer = GPT2Tokenizer.from_pretrained("openai-community/gpt2")
+model = GPT2LMHeadModel.from_pretrained("openai-community/gpt2")
+
+inputs = tokenizer("Hello, my dog is cute and ", return_tensors="pt")
+generation_output = model.generate(**inputs, return_dict_in_generate=True, output_scores=True)
+```
+
+`generation_output` 객체는 [`~generation.GenerateDecoderOnlyOutput`]입니다. 아래 문서에서 확인할 수 있듯이, 이 클래스는 다음과 같은 속성을 가지고 있습니다:
+
+- `sequences`: 생성된 토큰 시퀀스
+- `scores` (옵션): 각 생성 단계에서 언어 모델링 헤드의 예측 점수
+- `hidden_states` (옵션): 각 생성 단계에서 모델의 은닉 상태
+- `attentions` (옵션): 각 생성 단계에서 모델의 어텐션 가중치
+
+`output_scores=True`를 전달했기 때문에 `scores`는 포함되어 있지만, `output_hidden_states=True` 또는 `output_attentions=True`를 전달하지 않았으므로 `hidden_states`와 `attentions`는 포함되지 않았습니다.
+
+각 속성은 일반적으로 접근할 수 있으며, 모델이 해당 속성을 반환하지 않았다면 `None`이 반환됩니다. 예를 들어, `generation_output.scores`는 언어 모델링 헤드에서 생성된 모든 예측 점수를 포함하고 있으며, `generation_output.attentions`는 `None`입니다.
+
+`generation_output` 객체를 튜플로 사용할 경우, `None` 값이 아닌 속성만 포함됩니다. 예를 들어, `loss`와 `logits`라는 두 요소가 포함된 경우:
+
+```python
+generation_output[:2]
+```
+
+위 코드는 `(generation_output.sequences, generation_output.scores)` 튜플을 반환합니다.
+
+`generation_output` 객체를 딕셔너리로 사용할 경우, `None` 값이 아닌 속성만 포함됩니다. 예를 들어, `sequences`와 `scores`라는 두 개의 키를 가질 수 있습니다.
+
+여기서는 모든 출력 유형을 문서화합니다.
+
+
+### PyTorch [[transformers.generation.GenerateDecoderOnlyOutput]]
+
+[[autodoc]] generation.GenerateDecoderOnlyOutput
+
+[[autodoc]] generation.GenerateEncoderDecoderOutput
+
+[[autodoc]] generation.GenerateBeamDecoderOnlyOutput
+
+[[autodoc]] generation.GenerateBeamEncoderDecoderOutput
+
+### TensorFlow [[transformers.generation.TFGreedySearchEncoderDecoderOutput]]
+
+[[autodoc]] generation.TFGreedySearchEncoderDecoderOutput
+
+[[autodoc]] generation.TFGreedySearchDecoderOnlyOutput
+
+[[autodoc]] generation.TFSampleEncoderDecoderOutput
+
+[[autodoc]] generation.TFSampleDecoderOnlyOutput
+
+[[autodoc]] generation.TFBeamSearchEncoderDecoderOutput
+
+[[autodoc]] generation.TFBeamSearchDecoderOnlyOutput
+
+[[autodoc]] generation.TFBeamSampleEncoderDecoderOutput
+
+[[autodoc]] generation.TFBeamSampleDecoderOnlyOutput
+
+[[autodoc]] generation.TFContrastiveSearchEncoderDecoderOutput
+
+[[autodoc]] generation.TFContrastiveSearchDecoderOnlyOutput
+
+### FLAX [[transformers.generation.FlaxSampleOutput]]
+
+[[autodoc]] generation.FlaxSampleOutput
+
+[[autodoc]] generation.FlaxGreedySearchOutput
+
+[[autodoc]] generation.FlaxBeamSearchOutput
+
+## LogitsProcessor [[logitsprocessor]]
+
+[`LogitsProcessor`]는 생성 중 언어 모델 헤드의 예측 점수를 수정하는 데 사용됩니다.
+
+### PyTorch [[transformers.AlternatingCodebooksLogitsProcessor]]
+
+[[autodoc]] AlternatingCodebooksLogitsProcessor
+ - __call__
+
+[[autodoc]] ClassifierFreeGuidanceLogitsProcessor
+ - __call__
+
+[[autodoc]] EncoderNoRepeatNGramLogitsProcessor
+ - __call__
+
+[[autodoc]] EncoderRepetitionPenaltyLogitsProcessor
+ - __call__
+
+[[autodoc]] EpsilonLogitsWarper
+ - __call__
+
+[[autodoc]] EtaLogitsWarper
+ - __call__
+
+[[autodoc]] ExponentialDecayLengthPenalty
+ - __call__
+
+[[autodoc]] ForcedBOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] ForcedEOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] HammingDiversityLogitsProcessor
+ - __call__
+
+[[autodoc]] InfNanRemoveLogitsProcessor
+ - __call__
+
+[[autodoc]] LogitNormalization
+ - __call__
+
+[[autodoc]] LogitsProcessor
+ - __call__
+
+[[autodoc]] LogitsProcessorList
+ - __call__
+
+[[autodoc]] MinLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] MinNewTokensLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] MinPLogitsWarper
+ - __call__
+
+[[autodoc]] NoBadWordsLogitsProcessor
+ - __call__
+
+[[autodoc]] NoRepeatNGramLogitsProcessor
+ - __call__
+
+[[autodoc]] PrefixConstrainedLogitsProcessor
+ - __call__
+
+[[autodoc]] RepetitionPenaltyLogitsProcessor
+ - __call__
+
+[[autodoc]] SequenceBiasLogitsProcessor
+ - __call__
+
+[[autodoc]] SuppressTokensAtBeginLogitsProcessor
+ - __call__
+
+[[autodoc]] SuppressTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] TemperatureLogitsWarper
+ - __call__
+
+[[autodoc]] TopKLogitsWarper
+ - __call__
+
+[[autodoc]] TopPLogitsWarper
+ - __call__
+
+[[autodoc]] TypicalLogitsWarper
+ - __call__
+
+[[autodoc]] UnbatchedClassifierFreeGuidanceLogitsProcessor
+ - __call__
+
+[[autodoc]] WhisperTimeStampLogitsProcessor
+ - __call__
+
+[[autodoc]] WatermarkLogitsProcessor
+ - __call__
+
+
+### TensorFlow [[transformers.TFForcedBOSTokenLogitsProcessor]]
+
+[[autodoc]] TFForcedBOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] TFForcedEOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] TFForceTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] TFLogitsProcessor
+ - __call__
+
+[[autodoc]] TFLogitsProcessorList
+ - __call__
+
+[[autodoc]] TFLogitsWarper
+ - __call__
+
+[[autodoc]] TFMinLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] TFNoBadWordsLogitsProcessor
+ - __call__
+
+[[autodoc]] TFNoRepeatNGramLogitsProcessor
+ - __call__
+
+[[autodoc]] TFRepetitionPenaltyLogitsProcessor
+ - __call__
+
+[[autodoc]] TFSuppressTokensAtBeginLogitsProcessor
+ - __call__
+
+[[autodoc]] TFSuppressTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] TFTemperatureLogitsWarper
+ - __call__
+
+[[autodoc]] TFTopKLogitsWarper
+ - __call__
+
+[[autodoc]] TFTopPLogitsWarper
+ - __call__
+
+### FLAX [[transformers.FlaxForcedBOSTokenLogitsProcessor]]
+
+[[autodoc]] FlaxForcedBOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxForcedEOSTokenLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxForceTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxLogitsProcessorList
+ - __call__
+
+[[autodoc]] FlaxLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxMinLengthLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxSuppressTokensAtBeginLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxSuppressTokensLogitsProcessor
+ - __call__
+
+[[autodoc]] FlaxTemperatureLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxTopKLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxTopPLogitsWarper
+ - __call__
+
+[[autodoc]] FlaxWhisperTimeStampLogitsProcessor
+ - __call__
+
+## StoppingCriteria [[transformers.StoppingCriteria]]
+
+[`StoppingCriteria`]는 생성이 언제 멈출지를 결정하는 데 사용됩니다 (EOS 토큰 외). 이 기능은 PyTorch 구현에만 제공됩니다.
+
+[[autodoc]] StoppingCriteria
+ - __call__
+
+[[autodoc]] StoppingCriteriaList
+ - __call__
+
+[[autodoc]] MaxLengthCriteria
+ - __call__
+
+[[autodoc]] MaxTimeCriteria
+ - __call__
+
+[[autodoc]] StopStringCriteria
+ - __call__
+
+[[autodoc]] EosTokenCriteria
+ - __call__
+
+## Constraint [[transformers.Constraint]]
+
+[`Constraint`]는 생성 출력에 특정 토큰이나 시퀀스를 강제로 포함시키는 데 사용됩니다. 이 기능은 PyTorch 구현에만 제공됩니다.
+
+[[autodoc]] Constraint
+
+[[autodoc]] PhrasalConstraint
+
+[[autodoc]] DisjunctiveConstraint
+
+[[autodoc]] ConstraintListState
+
+## 빔 검색 (BeamSearch) [[transformers.BeamScorer]]
+
+[[autodoc]] BeamScorer
+ - process
+ - finalize
+
+[[autodoc]] BeamSearchScorer
+ - process
+ - finalize
+
+[[autodoc]] ConstrainedBeamSearchScorer
+ - process
+ - finalize
+
+## 스트리머 (Streamers) [[transformers.TextStreamer]]
+
+[[autodoc]] TextStreamer
+
+[[autodoc]] TextIteratorStreamer
+
+## 캐시 (Caches) [[transformers.Cache]]
+
+[[autodoc]] Cache
+ - update
+
+[[autodoc]] CacheConfig
+ - update
+
+[[autodoc]] QuantizedCacheConfig
+ - validate
+
+[[autodoc]] DynamicCache
+ - update
+ - get_seq_length
+ - reorder_cache
+ - to_legacy_cache
+ - from_legacy_cache
+
+[[autodoc]] QuantizedCache
+ - update
+ - get_seq_length
+
+[[autodoc]] QuantoQuantizedCache
+
+[[autodoc]] HQQQuantizedCache
+
+[[autodoc]] SinkCache
+ - update
+ - get_seq_length
+ - reorder_cache
+
+[[autodoc]] OffloadedCache
+ - update
+ - prefetch_layer
+ - evict_previous_layer
+
+[[autodoc]] StaticCache
+ - update
+ - get_seq_length
+ - reset
+
+[[autodoc]] OffloadedStaticCache
+ - update
+ - get_seq_length
+ - reset
+
+[[autodoc]] HybridCache
+ - update
+ - get_seq_length
+ - reset
+
+[[autodoc]] SlidingWindowCache
+ - update
+ - reset
+
+[[autodoc]] EncoderDecoderCache
+ - get_seq_length
+ - to_legacy_cache
+ - from_legacy_cache
+ - reset
+ - reorder_cache
+
+[[autodoc]] MambaCache
+ - update_conv_state
+ - update_ssm_state
+ - reset
+
+## 워터마크 유틸리티 (Watermark Utils) [[transformers.WatermarkDetector]]
+
+[[autodoc]] WatermarkDetector
+ - __call__
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/image_processing_utils.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/image_processing_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..cd32935132af8798cffa646b1c4e987834a617ee
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/image_processing_utils.md
@@ -0,0 +1,47 @@
+
+
+# 이미지 프로세서를 위한 유틸리티 [[utilities-for-image-processors]]
+
+이 페이지는 이미지 프로세서에서 사용되는 유틸리티 함수들을 나열하며, 주로 이미지를 처리하기 위한 함수 기반의 변환 작업들을 다룹니다.
+
+이 함수들 대부분은 라이브러리의 이미지 프로세서 코드를 연구할 때만 유용합니다.
+
+## 이미지 변환 [[transformers.image_transforms.center_crop]]
+
+[[autodoc]] image_transforms.center_crop
+
+[[autodoc]] image_transforms.center_to_corners_format
+
+[[autodoc]] image_transforms.corners_to_center_format
+
+[[autodoc]] image_transforms.id_to_rgb
+
+[[autodoc]] image_transforms.normalize
+
+[[autodoc]] image_transforms.pad
+
+[[autodoc]] image_transforms.rgb_to_id
+
+[[autodoc]] image_transforms.rescale
+
+[[autodoc]] image_transforms.resize
+
+[[autodoc]] image_transforms.to_pil_image
+
+## ImageProcessingMixin [[transformers.ImageProcessingMixin]]
+
+[[autodoc]] image_processing_utils.ImageProcessingMixin
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/modeling_utils.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/modeling_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..76cc09db292acdcaf3801713f28f19926ac6e314
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/modeling_utils.md
@@ -0,0 +1,83 @@
+
+
+# 사용자 정의 레이어 및 유틸리티 [[custom-layers-and-utilities]]
+
+이 페이지는 라이브러리에서 사용되는 사용자 정의 레이어와 모델링을 위한 유틸리티 함수들을 나열합니다.
+
+이 함수들 대부분은 라이브러리 내의 모델 코드를 연구할 때만 유용합니다.
+
+
+## PyTorch 사용자 정의 모듈 [[transformers.Conv1D]]
+
+[[autodoc]] pytorch_utils.Conv1D
+
+[[autodoc]] modeling_utils.PoolerStartLogits
+ - forward
+
+[[autodoc]] modeling_utils.PoolerEndLogits
+ - forward
+
+[[autodoc]] modeling_utils.PoolerAnswerClass
+ - forward
+
+[[autodoc]] modeling_utils.SquadHeadOutput
+
+[[autodoc]] modeling_utils.SQuADHead
+ - forward
+
+[[autodoc]] modeling_utils.SequenceSummary
+ - forward
+
+## PyTorch 헬퍼(helper) 함수 [[transformers.apply_chunking_to_forward]]
+
+[[autodoc]] pytorch_utils.apply_chunking_to_forward
+
+[[autodoc]] pytorch_utils.find_pruneable_heads_and_indices
+
+[[autodoc]] pytorch_utils.prune_layer
+
+[[autodoc]] pytorch_utils.prune_conv1d_layer
+
+[[autodoc]] pytorch_utils.prune_linear_layer
+
+## TensorFlow 사용자 정의 레이어 [[transformers.modeling_tf_utils.TFConv1D]]
+
+[[autodoc]] modeling_tf_utils.TFConv1D
+
+[[autodoc]] modeling_tf_utils.TFSequenceSummary
+
+## TensorFlow 손실 함수 [[transformers.modeling_tf_utils.TFCausalLanguageModelingLoss]]
+
+[[autodoc]] modeling_tf_utils.TFCausalLanguageModelingLoss
+
+[[autodoc]] modeling_tf_utils.TFMaskedLanguageModelingLoss
+
+[[autodoc]] modeling_tf_utils.TFMultipleChoiceLoss
+
+[[autodoc]] modeling_tf_utils.TFQuestionAnsweringLoss
+
+[[autodoc]] modeling_tf_utils.TFSequenceClassificationLoss
+
+[[autodoc]] modeling_tf_utils.TFTokenClassificationLoss
+
+## TensorFlow 도우미 함수 [[transformers.modeling_tf_utils.get_initializer]]
+
+[[autodoc]] modeling_tf_utils.get_initializer
+
+[[autodoc]] modeling_tf_utils.keras_serializable
+
+[[autodoc]] modeling_tf_utils.shape_list
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/pipelines_utils.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/pipelines_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..e0e64913145541cc4381df0562861c2b364f1cf2
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/pipelines_utils.md
@@ -0,0 +1,43 @@
+
+
+# 파이프라인을 위한 유틸리티 [[utilities-for-pipelines]]
+
+이 페이지는 라이브러리에서 파이프라인을 위해 제공하는 모든 유틸리티 함수들을 나열합니다.
+
+이 함수들 대부분은 라이브러리 내 모델의 코드를 연구할 때만 유용합니다.
+
+## 인자 처리 [[transformers.pipelines.ArgumentHandler]]
+
+[[autodoc]] pipelines.ArgumentHandler
+
+[[autodoc]] pipelines.ZeroShotClassificationArgumentHandler
+
+[[autodoc]] pipelines.QuestionAnsweringArgumentHandler
+
+## 데이터 형식 [[transformers.PipelineDataFormat]]
+
+[[autodoc]] pipelines.PipelineDataFormat
+
+[[autodoc]] pipelines.CsvPipelineDataFormat
+
+[[autodoc]] pipelines.JsonPipelineDataFormat
+
+[[autodoc]] pipelines.PipedPipelineDataFormat
+
+## 유틸리티 [[transformers.pipelines.PipelineException]]
+
+[[autodoc]] pipelines.PipelineException
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/time_series_utils.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/time_series_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..5729924575b87332223aa5db6c56b6735777b4db
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/time_series_utils.md
@@ -0,0 +1,29 @@
+
+
+# 시계열 유틸리티 [[time-series-utilities]]
+
+이 페이지는 시계열 기반 모델에서 사용할 수 있는 유틸리티 함수와 클래스들을 나열합니다.
+
+이 함수들 대부분은 시계열 모델의 코드를 연구하거나 분포 출력 클래스의 컬렉션에 추가하려는 경우에만 유용합니다.
+
+## 분포 출력 (Distributional Output) [[transformers.time_series_utils.NormalOutput]]
+
+[[autodoc]] time_series_utils.NormalOutput
+
+[[autodoc]] time_series_utils.StudentTOutput
+
+[[autodoc]] time_series_utils.NegativeBinomialOutput
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/tokenization_utils.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/tokenization_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..b5b69910479a2fb42aeaf4d8bd366967ea9f53e7
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/tokenization_utils.md
@@ -0,0 +1,39 @@
+
+
+# 토크나이저를 위한 유틸리티 [[utilities-for-tokenizers]]
+
+이 페이지는 토크나이저에서 사용되는 모든 유틸리티 함수들을 나열하며, 주로 [`PreTrainedTokenizer`]와 [`PreTrainedTokenizerFast`] 사이의 공통 메소드를 구현하는 [`~tokenization_utils_base.PreTrainedTokenizerBase`] 클래스와 [`~tokenization_utils_base.SpecialTokensMixin`]을 다룹니다.
+
+이 함수들 대부분은 라이브러리의 토크나이저 코드를 연구할 때만 유용합니다.
+
+## PreTrainedTokenizerBase [[transformers.PreTrainedTokenizerBase]]
+
+[[autodoc]] tokenization_utils_base.PreTrainedTokenizerBase
+ - __call__
+ - all
+
+## SpecialTokensMixin [[transformers.SpecialTokensMixin]]
+
+[[autodoc]] tokenization_utils_base.SpecialTokensMixin
+
+## Enums 및 namedtuples [[transformers.tokenization_utils_base.TruncationStrategy]]
+
+[[autodoc]] tokenization_utils_base.TruncationStrategy
+
+[[autodoc]] tokenization_utils_base.CharSpan
+
+[[autodoc]] tokenization_utils_base.TokenSpan
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/trainer_utils.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/trainer_utils.md
new file mode 100644
index 0000000000000000000000000000000000000000..15fb457331811c6b8cfce23a53766057e816a058
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/internal/trainer_utils.md
@@ -0,0 +1,49 @@
+
+
+# Trainer를 위한 유틸리티 (Utilities for Trainer) [[utilities-for-trainer]]
+
+이 페이지는 [`Trainer`]에서 사용되는 모든 유틸리티 함수들을 나열합니다.
+
+이 함수들 대부분은 라이브러리에 있는 Trainer 코드를 자세히 알아보고 싶을 때만 유용합니다.
+
+## 유틸리티 (Utilities) [[transformers.EvalPrediction]]
+
+[[autodoc]] EvalPrediction
+
+[[autodoc]] IntervalStrategy
+
+[[autodoc]] enable_full_determinism
+
+[[autodoc]] set_seed
+
+[[autodoc]] torch_distributed_zero_first
+
+## 콜백 내부 (Callbacks internals) [[transformers.trainer_callback.CallbackHandler]]
+
+[[autodoc]] trainer_callback.CallbackHandler
+
+## 분산 평가 (Distributed Evaluation) [[transformers.trainer_pt_utils.DistributedTensorGatherer]]
+
+[[autodoc]] trainer_pt_utils.DistributedTensorGatherer
+
+## Trainer 인자 파서 (Trainer Argument Parser) [[transformers.HfArgumentParser]]
+
+[[autodoc]] HfArgumentParser
+
+## 디버그 유틸리티 (Debug Utilities) [[transformers.debug_utils.DebugUnderflowOverflow]]
+
+[[autodoc]] debug_utils.DebugUnderflowOverflow
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/llm_optims.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/llm_optims.md
new file mode 100644
index 0000000000000000000000000000000000000000..99eabc19ce860aa78531e6bf4f0e8c1ca6f43f6e
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/llm_optims.md
@@ -0,0 +1,410 @@
+
+
+# LLM 추론 최적화 [[llm-inference-optimization]]
+
+대규모 언어 모델(LLM)은 채팅 및 코드 완성 모델과 같은 텍스트 생성 응용 프로그램을 한 단계 끌어올리며, 높은 수준의 이해력과 유창함을 보여주는 텍스트를 생성합니다. 그러나 LLM을 강력하게 만드는 요소인 그들의 크기는 동시에 추론 과정에서 도전 과제가 되기도 합니다.
+
+기본적인 추론은 느립니다, 왜냐하면 LLM이 다음 토큰을 생성하기 위해 반복적으로 호출되어야 하기 때문입니다. 생성이 진행됨에 따라 입력 시퀀스가 길어져 처리 시간이 점점 길어집니다. 또한, LLM은 수십억 개의 매개변수를 가지고 있어 모든 가중치를 메모리에 저장하고 처리하는 데 어려움이 있습니다.
+
+이 가이드는 LLM 추론을 가속하기 위해 Transformers에서 사용할 수 있는 최적화 기술을 사용하는 방법을 보여줍니다.
+
+> [!TIP]
+> Hugging Face는 LLM을 추론에 최적화하여 배포하고 서비스하는 데 전념하는 라이브러리인 [Text Generation Inference (TGI)](https://hf.co/docs/text-generation-inference)을 제공합니다. 이 라이브러리는 처리량 증가를 위한 지속적인 배칭과 다중 GPU 추론을 위한 텐서 병렬화와 같은 Transformers에 포함되지 않은 배포 지향 최적화 기능을 포함합니다.
+
+## 정적 kv-cache와 `torch.compile`[[static-kv-cache-and-torchcompile]]
+
+디코딩 중에 LLM은 각 입력 토큰에 대한 key-value(kv) 값을 계산합니다. LLM은 자기회귀(autoregressive)이기 때문에 생성된 출력이 현재 입력의 일부가 되어 매번 동일한 kv 값을 계산합니다. 이는 매번 동일한 kv 값을 다시 계산하기 때문에 효율적이지 않습니다.
+
+이를 최적화하기 위해, 이전 키(key)와 값(value)을 재계산하지 않고 저장하는 kv-cache를 사용할 수 있습니다. 그러나 kv-cache는 각 생성 단계에서 증가하며 동적이기 때문에 PyTorch 코드를 빠르고 최적화된 커널로 통합하는 강력한 최적화 도구인 [`torch.compile`](./perf_torch_compile)을 사용하는 데 제약이 있습니다.
+
+*정적 kv-cache*는 최댓값을 미리 할당하여 이 문제를 해결하여 `torch.compile`과 결합할 수 있게 합니다. 이를 통해 최대 4배의 속도 향상이 가능합니다. 속도 향상은 모델 크기(더 큰 모델은 속도 향상이 적음)와 하드웨어에 따라 다를 수 있습니다.
+
+> [!WARNING]
+현재 [Llama](./model_doc/llama2) 및 몇 가지 다른 모델만 정적 kv-cache와 `torch.compile`을 지원합니다. 실시간 모델 호환성 목록은 [이 이슈](https://github.com/huggingface/transformers/issues/28981)를 확인하십시오.
+
+작업의 복잡성에 따라 세 가지 방식의 정적 kv-cache 사용 방법이 있습니다:
+1. 기본 사용법: `generation_config`에서 플래그를 설정하기만 하면 됩니다(권장);
+2. 고급 사용법: 여러 번의 생성이나 맞춤형 생성 루프를 위해 캐시 객체를 처리합니다;
+3. 고급 사용법: 단일 그래프가 필요한 경우, 전체 `generate` 함수를 하나의 그래프로 컴파일합니다.
+
+올바른 탭을 선택하여 각 방법에 대한 추가 지침을 확인하세요.
+
+> [!TIP]
+> `torch.compile`을 사용할 때 어떤 전략을 사용하든, LLM 입력을 제한된 값 세트로 왼쪽에 패딩하면 모양과 관련된 재컴파일을 피할 수 있습니다. [`pad_to_multiple_of` tokenizer flag](https://huggingface.co/docs/transformers/main_classes/tokenizer#transformers.PreTrainedTokenizer.__call__.pad_to_multiple_of)가 유용할 것입니다!
+
+
+
+
+이 예제에서는 [Gemma](https://hf.co/google/gemma-2b) 모델을 사용해 보겠습니다. 필요한 작업은 다음과 같습니다:
+1. 모델의 `generation_config` 속성에 접근하여 `cache_implementation`을 "static"으로 설정합니다;
+2. 모델의 `forward` 패스를 정적 kv-cache와 함께 컴파일하기 위해 `torch.compile`을 호출합니다.
+
+이렇게 하면 끝입니다!
+
+```py
+from transformers import AutoTokenizer, AutoModelForCausalLM
+import torch
+import os
+os.environ["TOKENIZERS_PARALLELISM"] = "false" # 긴 경고 메시지를 방지하기 위해 설정 :)
+
+tokenizer = AutoTokenizer.from_pretrained("google/gemma-2b")
+model = AutoModelForCausalLM.from_pretrained("google/gemma-2b", device_map="auto")
+
+model.generation_config.cache_implementation = "static"
+
+model.forward = torch.compile(model.forward, mode="reduce-overhead", fullgraph=True)
+input_text = "The theory of special relativity states "
+input_ids = tokenizer(input_text, return_tensors="pt").to("cuda")
+
+outputs = model.generate(**input_ids)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['The theory of special relativity states 1. The speed of light is constant in all inertial reference']
+```
+
+`generate` 함수는 내부적으로 동일한 캐시 객체를 재사용하려고 시도하며, 이를 통해 각 호출 시 재컴파일의 필요성을 제거합니다. 재컴파일을 피하는 것은 `torch.compile`의 성능을 최대한 활용하는 데 매우 중요하며, 다음 사항에 유의해야 합니다:
+1. 배치 크기가 변경되거나 호출 간 최대 출력 길이가 증가하면 캐시를 다시 초기화해야 하며, 이로 인해 새로 컴파일을 해야 합니다;
+2. 컴파일된 함수의 첫 몇 번의 호출은 함수가 컴파일되는 동안 더 느립니다.
+
+> [!WARNING]
+> 다중 턴 대화와 같은 정적 캐시의 고급 사용을 위해서는, 캐시 객체를 [`~GenerationMixin.generate`] 외부에서 인스턴스화하고 조작하는 것을 권장합니다. 고급 사용법 탭을 참조하세요.
+
+
+
+
+[`StaticCache`] 객체는 `past_key_values` 인수로 모델의 [`~GenerationMixin.generate`] 함수에 전달할 수 있습니다. 이 객체는 캐시 내용을 유지하므로, 동적 캐시를 사용하는 것처럼 새로운 [`~GenerationMixin.generate`] 호출에 이를 전달하여 생성을 계속할 수 있습니다.
+
+```py
+from transformers import AutoTokenizer, AutoModelForCausalLM, StaticCache
+import torch
+import os
+os.environ["TOKENIZERS_PARALLELISM"] = "false" # 긴 경고 메시지를 방지하기 위해 설정 :)
+
+tokenizer = AutoTokenizer.from_pretrained("google/gemma-2b")
+model = AutoModelForCausalLM.from_pretrained("google/gemma-2b", device_map="auto")
+
+model.forward = torch.compile(model.forward, mode="reduce-overhead", fullgraph=True)
+input_text = "The theory of special relativity states "
+input_ids = tokenizer(input_text, return_tensors="pt").to("cuda")
+prompt_length = input_ids.input_ids.shape[1]
+model.generation_config.max_new_tokens = 16
+
+past_key_values = StaticCache(
+ config=model.config,
+ batch_size=1,
+ # 캐시를 재사용할 계획이 있는 경우, 모든 경우에 충분한 캐시 길이를 설정해야 합니다
+ max_cache_len=prompt_length+(model.generation_config.max_new_tokens*2),
+ device=model.device,
+ dtype=model.dtype
+)
+outputs = model.generate(**input_ids, past_key_values=past_key_values)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['The theory of special relativity states 1. The speed of light is constant in all inertial reference frames. 2']
+
+# 생성된 텍스트와 동일한 캐시 객체를 전달하여, 중단한 곳에서 생성을 계속합니다.
+# 다중 턴 대화의 경우, 생성된 텍스트에 새로운 사용자 입력을 추가할 수 있습니다.
+new_input_ids = outputs
+outputs = model.generate(new_input_ids, past_key_values=past_key_values)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['The theory of special relativity states 1. The speed of light is constant in all inertial reference frames. 2. The speed of light is constant in all inertial reference frames. 3.']
+```
+
+> [!TIP]
+> 동일한 [`StaticCache`] 객체를 새로운 프롬프트에 사용하려면, 호출 간에 `.reset()` 메서드를 사용하여 그 내용을 초기화하는 것이 좋습니다.
+
+더 깊이 들어가고 싶다면, [`StaticCache`] 객체를 모델의 `forward` 패스에 동일한 `past_key_values` 인수로 전달할 수도 있습니다. 이 전략을 사용하면, 현재 토큰과 이전에 생성된 토큰의 위치 및 캐시 위치를 바탕으로 다음 토큰을 디코딩하는 자체 함수를 작성할 수 있습니다.
+
+```py
+from transformers import LlamaTokenizer, LlamaForCausalLM, StaticCache, logging
+from transformers.testing_utils import CaptureLogger
+import torch
+
+prompts = [
+ "Simply put, the theory of relativity states that ",
+ "My favorite all time favorite condiment is ketchup.",
+]
+
+NUM_TOKENS_TO_GENERATE = 40
+torch_device = "cuda"
+
+tokenizer = LlamaTokenizer.from_pretrained("meta-llama/Llama-2-7b-hf", pad_token="", padding_side="right")
+model = LlamaForCausalLM.from_pretrained("meta-llama/Llama-2-7b-hf", device_map="sequential")
+inputs = tokenizer(prompts, return_tensors="pt", padding=True).to(model.device)
+
+def decode_one_tokens(model, cur_token, input_pos, cache_position, past_key_values):
+ logits = model(
+ cur_token,
+ position_ids=input_pos,
+ cache_position=cache_position,
+ past_key_values=past_key_values,
+ return_dict=False,
+ use_cache=True
+ )[0]
+ new_token = torch.argmax(logits[:, -1], dim=-1)[:, None]
+ return new_token
+```
+
+`StaticCache` 메서드를 사용하여 정적 kv-cache와 `torch.compile`을 활성화하려면 몇 가지 중요한 작업을 수행해야 합니다:
+1. 추론에 모델을 사용하기 전에 [`StaticCache`] 인스턴스를 초기화합니다. 여기서 최대 배치 크기와 시퀀스 길이와 같은 매개변수를 설정할 수 있습니다.
+2. 정적 kv-cache와 함께 순전파를 컴파일하기 위해 모델에 `torch.compile`을 호출합니다.
+3. [torch.backends.cuda.sdp_kernel](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention.html) 컨텍스트 관리자에서 `enable_math=True`를 설정하여 네이티브 PyTorch C++ 구현된 스케일된 점곱 어텐션(scaled dot product attention)을 활성화하여 추론 속도를 더욱 높입니다.
+
+```py
+batch_size, seq_length = inputs["input_ids"].shape
+with torch.no_grad():
+ past_key_values = StaticCache(
+ config=model.config, max_batch_size=2, max_cache_len=4096, device=torch_device, dtype=model.dtype
+ )
+ cache_position = torch.arange(seq_length, device=torch_device)
+ generated_ids = torch.zeros(
+ batch_size, seq_length + NUM_TOKENS_TO_GENERATE + 1, dtype=torch.int, device=torch_device
+ )
+ generated_ids[:, cache_position] = inputs["input_ids"].to(torch_device).to(torch.int)
+
+ logits = model(
+ **inputs, cache_position=cache_position, past_key_values=past_key_values,return_dict=False, use_cache=True
+ )[0]
+ next_token = torch.argmax(logits[:, -1], dim=-1)[:, None]
+ generated_ids[:, seq_length] = next_token[:, 0]
+
+ decode_one_tokens = torch.compile(decode_one_tokens, mode="reduce-overhead", fullgraph=True)
+ cache_position = torch.tensor([seq_length + 1], device=torch_device)
+ for _ in range(1, NUM_TOKENS_TO_GENERATE):
+ with torch.backends.cuda.sdp_kernel(enable_flash=False, enable_mem_efficient=False, enable_math=True):
+ next_token = decode_one_tokens(model, next_token.clone(), None, cache_position, past_key_values)
+ generated_ids[:, cache_position] = next_token.int()
+ cache_position += 1
+
+text = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+text
+['Simply put, the theory of relativity states that 1) the speed of light is constant, 2) the speed of light is the same for all observers, and 3) the laws of physics are the same for all observers.',
+ 'My favorite all time favorite condiment is ketchup. I love it on everything. I love it on my eggs, my fries, my chicken, my burgers, my hot dogs, my sandwiches, my salads, my p']
+```
+
+
+
+
+전체 `generate` 함수를 컴파일하는 것은 코드 측면에서 기본 사용법보다 더 간단합니다. `generate` 함수에 대해 `torch.compile`을 호출하여 전체 함수를 컴파일하면 됩니다. 정적 캐시의 사용을 지정할 필요는 없습니다. 정적 캐시는 호환되지만, 벤치마크에서는 동적 캐시(기본 설정)가 더 빠른 것으로 나타났습니다.
+
+```py
+from transformers import AutoTokenizer, AutoModelForCausalLM
+import torch
+import os
+os.environ["TOKENIZERS_PARALLELISM"] = "false" # 긴 경고 메시지를 방지하기 위해 설정 :)
+
+tokenizer = AutoTokenizer.from_pretrained("google/gemma-2b")
+model = AutoModelForCausalLM.from_pretrained("google/gemma-2b", device_map="auto")
+
+model.generate = torch.compile(model.generate, mode="reduce-overhead", fullgraph=True)
+input_text = "The theory of special relativity states "
+input_ids = tokenizer(input_text, return_tensors="pt").to("cuda")
+
+outputs = model.generate(**input_ids)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['The theory of special relativity states 1. The speed of light is constant in all inertial reference']
+```
+
+이 방법을 통해 모델의 forward 패스뿐만 아니라, 입력 준비, logit 처리기 작업 등을 포함한 모든 것을 컴파일합니다. 기본 사용 예제에 비해 `generate` 호출이 약간 더 빠를 수 있으며, 컴파일된 그래프는 더 특이한 하드웨어 장치나 사용 사례에 적합할 수 있습니다. 그러나 이 접근 방식을 사용하는 데는 몇 가지 큰 단점이 있습니다:
+1. 컴파일 속도가 훨씬 느립니다;
+2. `generate`의 모든 매개변수 설정은 `generation_config`를 통해서만 가능합니다;
+3. 많은 경고와 예외가 억제됩니다. -- 먼저 컴파일 되지 않은 형태로 테스트하는 것을 권장합니다;
+4. 현재 작업 중이지만 기능 제한이 심합니다(예: 작성 시점에서는 EOS 토큰이 선택되어도 생성이 중단되지 않습니다).
+
+
+
+
+## 추정 디코딩 [[speculative-decoding]]
+
+> [!TIP]
+> 보다 심층적인 설명을 원한다면, [Assisted Generation: a new direction toward low-latency text generation](https://hf.co/blog/assisted-generation) 블로그 게시물을 확인하십시오!
+
+자기 회귀의 또 다른 문제는 각 입력 토큰에 대해 순전파 중에 모델 가중치를 매번 로드해야 한다는 점입니다. 이는 수십억 개의 매개변수를 가진 LLM에는 느리고 번거롭습니다. 추정 디코딩(speculative decoding)은 더 작고 빠른 보조 모델을 사용하여 후보 토큰을 생성하고, 이를 큰 LLM이 단일 순전파에서 검증하여 이 속도 저하를 완화합니다. 검증된 토큰이 정확하다면, LLM은 본래 자체적으로 생성하는 것처럼 토큰을 얻을 수 있습니다. 전방 패스가 동일한 출력을 보장하기 때문에 정확도 저하가 없습니다.
+
+가장 큰 속도 향상을 얻기 위해, 보조 모델은 빠르게 토큰을 생성할 수 있도록 LLM보다 훨씬 작아야 합니다. 보조 모델과 LLM 모델은 토큰을 다시 인코딩하고 디코딩하지 않도록 동일한 토크나이저를 공유해야 합니다.
+
+> [!WARNING]
+> 추정 디코딩은 탐욕 검색과 샘플링 디코딩 전략에서만 지원되며, 배치 입력을 지원하지 않습니다.
+
+보조 모델을 로드하고 이를 [`~GenerationMixin.generate`] 메서드에 전달하여 추정 디코딩을 활성화하십시오.
+
+
+
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+import torch
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-1.3b")
+inputs = tokenizer("Einstein's theory of relativity states", return_tensors="pt").to(device)
+
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-1.3b").to(device)
+assistant_model = AutoModelForCausalLM.from_pretrained("facebook/opt-125m").to(device)
+outputs = model.generate(**inputs, assistant_model=assistant_model)
+tokenizer.batch_decode(outputs, skip_special_tokens=True)
+["Einstein's theory of relativity states that the speed of light is constant. "]
+```
+
+
+
+
+추정 샘플링 디코딩(speculative sampling decoding)을 위해, 보조 모델 외에도 [`~GenerationMixin.generate`] 메서드에 `do_sample` 및 `temperature` 매개변수를 추가하십시오.
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+import torch
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-1.3b")
+inputs = tokenizer("Einstein's theory of relativity states", return_tensors="pt").to(device)
+
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-1.3b").to(device)
+assistant_model = AutoModelForCausalLM.from_pretrained("facebook/opt-125m").to(device)
+outputs = model.generate(**inputs, assistant_model=assistant_model, do_sample=True, temperature=0.7)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+["Einstein's theory of relativity states that motion in the universe is not a straight line.\n"]
+```
+
+
+
+
+### 프롬프트 조회 디코딩 [[prompt-lookup-decoding]]
+
+프롬프트 조회 디코딩은 탐욕 검색과 샘플링과도 호환되는 추정 디코딩의 변형입니다. 프롬프트 조회는 요약과 같은 입력 기반 작업에 특히 잘 작동합니다. 여기서는 프롬프트와 출력 간에 종종 겹치는 단어가 있습니다. 이러한 겹치는 n-그램이 LLM 후보 토큰으로 사용됩니다.
+
+프롬프트 조회 디코딩을 활성화하려면 `prompt_lookup_num_tokens` 매개변수에 겹치는 토큰 수를 지정하십시오. 그런 다음 이 매개변수를 [`~GenerationMixin.generate`] 메서드에 전달할 수 있습니다.
+
+
+
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+import torch
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-1.3b")
+inputs = tokenizer("The second law of thermodynamics states", return_tensors="pt").to(device)
+
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-1.3b").to(device)
+assistant_model = AutoModelForCausalLM.from_pretrained("facebook/opt-125m").to(device)
+outputs = model.generate(**inputs, prompt_lookup_num_tokens=3)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['The second law of thermodynamics states that entropy increases with temperature. ']
+```
+
+
+
+
+샘플링과 함께 프롬프트 조회 디코딩을 사용하려면, [`~GenerationMixin.generate`] 메서드에 `do_sample` 및 `temperature` 매개변수를 추가하십시오.
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+import torch
+
+device = "cuda" if torch.cuda.is_available() else "cpu"
+
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-1.3b")
+inputs = tokenizer("The second law of thermodynamics states", return_tensors="pt").to(device)
+
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-1.3b").to(device)
+outputs = model.generate(**inputs, prompt_lookup_num_tokens=3, do_sample=True, temperature=0.7)
+print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+["The second law of thermodynamics states that energy cannot be created nor destroyed. It's not a"]
+```
+
+
+
+
+## 어텐션 최적화 [[attention-optimizations]]
+
+트랜스포머 모델의 알려진 문제는 셀프 어텐션 메커니즘이 입력 토큰 수와 함께 계산 및 메모리가 제곱으로 증가한다는 것입니다. 이 제한은 훨씬 더 긴 시퀀스를 처리하는 LLM에서는 더욱 커집니다. 이를 해결하기 위해 FlashAttention2 또는 PyTorch의 스케일된 점곱 어텐션을 사용해 보십시오. 이들은 더 메모리 효율적인 어텐션 구현으로 추론을 가속화할 수 있습니다.
+
+### FlashAttention-2 [[flashattention-2]]
+
+FlashAttention과 [FlashAttention-2](./perf_infer_gpu_one#flashattention-2)는 어텐션 계산을 더 작은 청크로 나누고 중간 읽기/쓰기 작업을 줄여 추론 속도를 높입니다. FlashAttention-2는 원래 FlashAttention 알고리즘을 개선하여 시퀀스 길이 차원에서도 병렬 처리를 수행하고 하드웨어에서 작업을 더 잘 분할하여 동기화 및 통신 오버헤드를 줄입니다.
+
+FlashAttention-2를 사용하려면 [`~PreTrainedModel.from_pretrained`] 메서드에서 `attn_implementation="flash_attention_2"`를 설정하십시오.
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quant_config = BitsAndBytesConfig(load_in_8bit=True)
+model = AutoModelForCausalLM.from_pretrained(
+ "google/gemma-2b",
+ quantization_config=quant_config,
+ torch_dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+)
+```
+
+### PyTorch 스케일된 점곱 어텐션(scaled dot product attention) [[pytorch-scaled-dot-product-attention]]
+
+스케일된 점곱 어텐션(SDPA)는 PyTorch 2.0에서 자동으로 활성화되며, FlashAttention, xFormers, PyTorch의 C++ 구현을 지원합니다. SDPA는 CUDA 백엔드를 사용하는 경우 가장 성능이 좋은 어텐션 알고리즘을 선택합니다. 다른 백엔드에서는 SDPA가 PyTorch C++ 구현으로 기본 설정됩니다.
+
+> [!TIP]
+> SDPA는 최신 PyTorch 버전이 설치되어 있으면 FlashAttention-2도 지원합니다.
+
+세 가지 어텐션 알고리즘 중 하나를 명시적으로 활성화하거나 비활성화하려면 [torch.backends.cuda.sdp_kernel](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention.html) 컨텍스트 관리자를 사용하십시오. 예를 들어 FlashAttention을 활성화하려면 `enable_flash=True`로 설정하십시오.
+
+```py
+import torch
+from transformers import AutoModelForCausalLM
+
+model = AutoModelForCausalLM.from_pretrained(
+ "google/gemma-2b",
+ torch_dtype=torch.bfloat16,
+)
+
+with torch.backends.cuda.sdp_kernel(enable_flash=True, enable_math=False, enable_mem_efficient=False):
+ outputs = model.generate(**inputs)
+```
+
+## 양자화 [[quantization]]
+
+양자화는 LLM 가중치를 더 낮은 정밀도로 저장하여 크기를 줄입니다. 이는 메모리 사용량을 줄이며 GPU 메모리에 제약이 있는 경우 추론을 위해 LLM을 로드하는 것을 더 용이하게 합니다. GPU가 충분하다면, 모델을 양자화할 필요는 없습니다. 추가적인 양자화 및 양자화 해제 단계로 인해 약간의 지연이 발생할 수 있기 때문입니다(AWQ 및 융합 AWQ 모듈 제외).
+
+> [!TIP]
+> 다양한 양자화 라이브러리(자세한 내용은 [Quantization](./quantization) 가이드를 참조하십시오)가 있습니다. 여기에는 Quanto, AQLM, VPTQ, AWQ 및 AutoGPTQ가 포함됩니다. 사용 사례에 가장 잘 맞는 라이브러리를 사용해 보십시오. 또한 AutoGPTQ와 bitsandbytes를 비교하는 [Overview of natively supported quantization schemes in 🤗 Transformers](https://hf.co/blog/overview-quantization-transformers) 블로그 게시물을 읽어보는 것을 추천합니다.
+
+아래의 모델 메모리 계산기를 사용하여 모델을 로드하는 데 필요한 메모리를 추정하고 비교해 보십시오. 예를 들어 [Mistral-7B-v0.1](https://huggingface.co/mistralai/Mistral-7B-v0.1)를 로드하는 데 필요한 메모리를 추정해 보십시오.
+
+
+
+Mistral-7B-v0.1을 반정밀도로 로드하려면 [`~transformers.AutoModelForCausalLM.from_pretrained`] 메서드에서 `torch_dtype` 매개변수를 `torch.bfloat16`으로 설정하십시오. 이 경우 13.74GB의 메모리가 필요합니다.
+
+```py
+from transformers import AutoTokenizer, AutoModelForCausalLM
+import torch
+
+model = AutoModelForCausalLM.from_pretrained(
+ "mistralai/Mistral-7B-v0.1", torch_dtype=torch.bfloat16, device_map="auto",
+)
+```
+
+추론을 위해 양자화된 모델(8비트 또는 4비트)을 로드하려면 [bitsandbytes](https://hf.co/docs/bitsandbytes)를 사용하고 `load_in_4bit` 또는 `load_in_8bit` 매개변수를 `True`로 설정하십시오. 모델을 8비트로 로드하는 데는 6.87GB의 메모리만 필요합니다.
+
+```py
+from transformers import AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig
+import torch
+
+quant_config = BitsAndBytesConfig(load_in_8bit=True)
+model = AutoModelForCausalLM.from_pretrained(
+ "mistralai/Mistral-7B-v0.1", quantization_config=quant_config, device_map="auto"
+)
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/llm_tutorial.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/llm_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..d5e0bd356edd2e8589e1f70a3ca65809d09c6d72
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/llm_tutorial.md
@@ -0,0 +1,222 @@
+
+
+
+# 대규모 언어 모델로 생성하기 [[generation-with-llms]]
+
+[[open-in-colab]]
+
+LLM 또는 대규모 언어 모델은 텍스트 생성의 핵심 구성 요소입니다. 간단히 말하면, 주어진 입력 텍스트에 대한 다음 단어(정확하게는 토큰)를 예측하기 위해 훈련된 대규모 사전 훈련 변환기 모델로 구성됩니다. 토큰을 한 번에 하나씩 예측하기 때문에 새로운 문장을 생성하려면 모델을 호출하는 것 외에 더 복잡한 작업을 수행해야 합니다. 즉, 자기회귀 생성을 수행해야 합니다.
+
+자기회귀 생성은 몇 개의 초기 입력값을 제공한 후, 그 출력을 다시 모델에 입력으로 사용하여 반복적으로 호출하는 추론 과정입니다. 🤗 Transformers에서는 [`~generation.GenerationMixin.generate`] 메소드가 이 역할을 하며, 이는 생성 기능을 가진 모든 모델에서 사용 가능합니다.
+
+이 튜토리얼에서는 다음 내용을 다루게 됩니다:
+
+* LLM으로 텍스트 생성
+* 일반적으로 발생하는 문제 해결
+* LLM을 최대한 활용하기 위한 다음 단계
+
+시작하기 전에 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers bitsandbytes>=0.39.0 -q
+```
+
+
+## 텍스트 생성 [[generate-text]]
+
+[인과적 언어 모델링(causal language modeling)](tasks/language_modeling)을 목적으로 학습된 언어 모델은 일련의 텍스트 토큰을 입력으로 사용하고, 그 결과로 다음 토큰이 나올 확률 분포를 제공합니다.
+
+
+
+
+ "LLM의 전방 패스"
+
+
+LLM과 자기회귀 생성을 함께 사용할 때 핵심적인 부분은 이 확률 분포로부터 다음 토큰을 어떻게 고를 것인지입니다. 다음 반복 과정에 사용될 토큰을 결정하는 한, 어떠한 방법도 가능합니다. 확률 분포에서 가장 가능성이 높은 토큰을 선택하는 것처럼 간단할 수도 있고, 결과 분포에서 샘플링하기 전에 수십 가지 변환을 적용하는 것처럼 복잡할 수도 있습니다.
+
+
+
+
+ "자기회귀 생성은 확률 분포에서 다음 토큰을 반복적으로 선택하여 텍스트를 생성합니다."
+
+
+위에서 설명한 과정은 어떤 종료 조건이 충족될 때까지 반복적으로 수행됩니다. 모델이 시퀀스의 끝(EOS 토큰)을 출력할 때까지를 종료 조건으로 하는 것이 이상적입니다. 그렇지 않은 경우에는 미리 정의된 최대 길이에 도달했을 때 생성이 중단됩니다.
+
+모델이 예상대로 동작하기 위해선 토큰 선택 단계와 정지 조건을 올바르게 설정하는 것이 중요합니다. 이러한 이유로, 각 모델에는 기본 생성 설정이 잘 정의된 [`~generation.GenerationConfig`] 파일이 함께 제공됩니다.
+
+코드를 확인해봅시다!
+
+
+
+기본 LLM 사용에 관심이 있다면, 우리의 [`Pipeline`](pipeline_tutorial) 인터페이스로 시작하는 것을 추천합니다. 그러나 LLM은 양자화나 토큰 선택 단계에서의 미세한 제어와 같은 고급 기능들을 종종 필요로 합니다. 이러한 작업은 [`~generation.GenerationMixin.generate`]를 통해 가장 잘 수행될 수 있습니다. LLM을 이용한 자기회귀 생성은 자원을 많이 소모하므로, 적절한 처리량을 위해 GPU에서 실행되어야 합니다.
+
+
+
+먼저, 모델을 불러오세요.
+
+```python
+>>> from transformers import AutoModelForCausalLM
+
+>>> model = AutoModelForCausalLM.from_pretrained(
+... "mistralai/Mistral-7B-v0.1", device_map="auto", load_in_4bit=True
+... )
+```
+
+`from_pretrained` 함수를 호출할 때 2개의 플래그를 주목하세요:
+
+- `device_map`은 모델이 GPU로 이동되도록 합니다.
+- `load_in_4bit`는 리소스 요구 사항을 크게 줄이기 위해 [4비트 동적 양자화](main_classes/quantization)를 적용합니다.
+
+이 외에도 모델을 초기화하는 다양한 방법이 있지만, LLM을 처음 시작할 때 이 설정을 추천합니다.
+
+이어서 텍스트 입력을 [토크나이저](tokenizer_summary)으로 전처리하세요.
+
+```python
+>>> from transformers import AutoTokenizer
+>>> import torch
+
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1")
+>>> device = "cuda" if torch.cuda.is_available() else "cpu"
+>>> model_inputs = tokenizer(["A list of colors: red, blue"], return_tensors="pt").to(device)
+```
+
+`model_inputs` 변수에는 토큰화된 텍스트 입력과 함께 어텐션 마스크가 들어 있습니다. [`~generation.GenerationMixin.generate`]는 어텐션 마스크가 제공되지 않았을 경우에도 이를 추론하려고 노력하지만, 최상의 성능을 위해서는 가능하면 어텐션 마스크를 전달하는 것을 권장합니다.
+
+마지막으로 [`~generation.GenerationMixin.generate`] 메소드를 호출해 생성된 토큰을 얻은 후, 이를 출력하기 전에 텍스트 형태로 변환하세요.
+
+```python
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'A list of colors: red, blue, green, yellow, black, white, and brown'
+```
+
+이게 전부입니다! 몇 줄의 코드만으로 LLM의 능력을 활용할 수 있게 되었습니다.
+
+
+## 일반적으로 발생하는 문제 [[common-pitfalls]]
+
+[생성 전략](generation_strategies)이 많고, 기본값이 항상 사용 사례에 적합하지 않을 수 있습니다. 출력이 예상과 다를 때 흔히 발생하는 문제와 이를 해결하는 방법에 대한 목록을 만들었습니다.
+
+```py
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1")
+>>> tokenizer.pad_token = tokenizer.eos_token # Mistral has no pad token by default
+>>> model = AutoModelForCausalLM.from_pretrained(
+... "mistralai/Mistral-7B-v0.1", device_map="auto", load_in_4bit=True
+... )
+```
+
+### 생성된 출력이 너무 짧거나 길다 [[generated-output-is-too-shortlong]]
+
+[`~generation.GenerationConfig`] 파일에서 별도로 지정하지 않으면, `generate`는 기본적으로 최대 20개의 토큰을 반환합니다. `generate` 호출에서 `max_new_tokens`을 수동으로 설정하여 반환할 수 있는 새 토큰의 최대 수를 설정하는 것이 좋습니다. LLM(정확하게는 [디코더 전용 모델](https://huggingface.co/learn/nlp-course/chapter1/6?fw=pt))은 입력 프롬프트도 출력의 일부로 반환합니다.
+
+
+```py
+>>> model_inputs = tokenizer(["A sequence of numbers: 1, 2"], return_tensors="pt").to("cuda")
+
+>>> # By default, the output will contain up to 20 tokens
+>>> generated_ids = model.generate(**model_inputs, pad_token_id=tokenizer.eos_token_id)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'A sequence of numbers: 1, 2, 3, 4, 5'
+
+>>> # Setting `max_new_tokens` allows you to control the maximum length
+>>> generated_ids = model.generate(**model_inputs, pad_token_id=tokenizer.eos_token_id, max_new_tokens=50)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'A sequence of numbers: 1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 12, 13, 14, 15, 16,'
+```
+
+### 잘못된 생성 모드 [[incorrect-generation-mode]]
+
+기본적으로 [`~generation.GenerationConfig`] 파일에서 별도로 지정하지 않으면, `generate`는 각 반복에서 가장 확률이 높은 토큰을 선택합니다(그리디 디코딩). 하려는 작업에 따라 이 방법은 바람직하지 않을 수 있습니다. 예를 들어, 챗봇이나 에세이 작성과 같은 창의적인 작업은 샘플링이 적합할 수 있습니다. 반면, 오디오를 텍스트로 변환하거나 번역과 같은 입력 기반 작업은 그리디 디코딩이 더 적합할 수 있습니다. `do_sample=True`로 샘플링을 활성화할 수 있으며, 이 주제에 대한 자세한 내용은 이 [블로그 포스트](https://huggingface.co/blog/how-to-generate)에서 볼 수 있습니다.
+
+```python
+>>> # Set seed or reproducibility -- you don't need this unless you want full reproducibility
+>>> from transformers import set_seed
+>>> set_seed(0)
+
+>>> model_inputs = tokenizer(["I am a cat."], return_tensors="pt").to("cuda")
+
+>>> # LLM + greedy decoding = repetitive, boring output
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'I am a cat. I am a cat. I am a cat. I am a cat'
+
+>>> # With sampling, the output becomes more creative!
+>>> generated_ids = model.generate(**model_inputs, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'I am a cat.\nI just need to be. I am always.\nEvery time'
+```
+
+### 잘못된 패딩 [[wrong-padding-side]]
+
+LLM은 [디코더 전용](https://huggingface.co/learn/nlp-course/chapter1/6?fw=pt) 구조를 가지고 있어, 입력 프롬프트에 대해 지속적으로 반복 처리를 합니다. 입력 데이터의 길이가 다르면 패딩 작업이 필요합니다. LLM은 패딩 토큰에서 작동을 이어가도록 설계되지 않았기 때문에, 입력 왼쪽에 패딩이 추가 되어야 합니다. 그리고 어텐션 마스크도 꼭 `generate` 함수에 전달되어야 합니다!
+
+```python
+>>> # The tokenizer initialized above has right-padding active by default: the 1st sequence,
+>>> # which is shorter, has padding on the right side. Generation fails.
+>>> model_inputs = tokenizer(
+... ["1, 2, 3", "A, B, C, D, E"], padding=True, return_tensors="pt"
+... ).to("cuda")
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids[0], skip_special_tokens=True)[0]
+''
+
+>>> # With left-padding, it works as expected!
+>>> tokenizer = AutoTokenizer.from_pretrained("openlm-research/open_llama_7b", padding_side="left")
+>>> tokenizer.pad_token = tokenizer.eos_token # Llama has no pad token by default
+>>> model_inputs = tokenizer(
+... ["1, 2, 3", "A, B, C, D, E"], padding=True, return_tensors="pt"
+... ).to("cuda")
+>>> generated_ids = model.generate(**model_inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+'1, 2, 3, 4, 5, 6,'
+```
+
+
+
+## 추가 자료 [[further-resources]]
+
+자기회귀 생성 프로세스는 상대적으로 단순한 편이지만, LLM을 최대한 활용하려면 여러 가지 요소를 고려해야 하므로 쉽지 않을 수 있습니다. LLM에 대한 더 깊은 이해와 활용을 위한 다음 단계는 아래와 같습니다:
+
+
+### 고급 생성 사용 [[advanced-generate-usage]]
+
+1. [가이드](generation_strategies)는 다양한 생성 방법을 제어하는 방법, 생성 설정 파일을 설정하는 방법, 출력을 스트리밍하는 방법에 대해 설명합니다.
+2. [`~generation.GenerationConfig`]와 [`~generation.GenerationMixin.generate`], [generate-related classes](internal/generation_utils)를 참조해보세요.
+
+### LLM 리더보드 [[llm-leaderboards]]
+
+1. [Open LLM Leaderboard](https://huggingface.co/spaces/HuggingFaceH4/open_llm_leaderboard)는 오픈 소스 모델의 품질에 중점을 둡니다.
+2. [Open LLM-Perf Leaderboard](https://huggingface.co/spaces/optimum/llm-perf-leaderboard)는 LLM 처리량에 중점을 둡니다.
+
+### 지연 시간 및 처리량 [[latency-and-throughput]]
+
+1. 메모리 요구 사항을 줄이려면, 동적 양자화에 대한 [가이드](main_classes/quantization)를 참조하세요.
+
+### 관련 라이브러리 [[related-libraries]]
+
+1. [`text-generation-inference`](https://github.com/huggingface/text-generation-inference)는 LLM을 위한 실제 운영 환경에 적합한 서버입니다.
+2. [`optimum`](https://github.com/huggingface/optimum)은 특정 하드웨어 장치에서 LLM을 최적화하기 위해 🤗 Transformers를 확장한 것입니다.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/llm_tutorial_optimization.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/llm_tutorial_optimization.md
new file mode 100644
index 0000000000000000000000000000000000000000..d43affd288fcd5e9b1589bbda634baa5dade67f3
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/llm_tutorial_optimization.md
@@ -0,0 +1,759 @@
+
+# 대규모 언어 모델의 속도 및 메모리 최적화 [[optimizing-llms-for-speed-and-memory]]
+
+[[open-in-colab]]
+
+GPT3/4, [Falcon](https://huggingface.co/tiiuae/falcon-40b), [Llama](https://huggingface.co/meta-llama/Llama-2-70b-hf)와 같은 대규모 언어 모델의 인간 중심 과제를 해결하는 능력이 빠르게 발전하고 있으며, 현대 지식 기반 산업에서 필수 도구로 자리잡고 있습니다. 그러나 이러한 모델을 실제 과제에 배포하는 것은 여전히 어려운 과제입니다.
+
+- 인간과 비슷한 텍스트 이해 및 생성 능력을 보이기 위해, 현재 대규모 언어 모델은 수십억 개의 매개변수로 구성되어야 합니다 (참조: [Kaplan et al](https://arxiv.org/abs/2001.08361), [Wei et. al](https://arxiv.org/abs/2206.07682)). 이는 추론을 위한 메모리 요구를 크게 증가시킵니다.
+- 많은 실제 과제에서 대규모 언어 모델은 방대한 맥락 정보를 제공받아야 합니다. 이는 모델이 추론 과정에서 매우 긴 입력 시퀀스를 처리할 수 있어야 한다는 것을 뜻합니다.
+
+이러한 과제의 핵심은 대규모 언어 모델의 계산 및 메모리 활용 능력을 증대시키는 데 있습니다. 특히 방대한 입력 시퀀스를 처리할 때 이러한 능력이 중요합니다.
+
+이 가이드에서는 효율적인 대규모 언어 모델 배포를 위한 효과적인 기법들을 살펴보겠습니다.
+
+1. **낮은 정밀도:** 연구에 따르면, [8비트와 4비트](./main_classes/quantization.md)와 같이 낮은 수치 정밀도로 작동하면 모델 성능의 큰 저하 없이 계산상의 이점을 얻을 수 있습니다.
+
+2. **플래시 어텐션:** 플래시 어텐션은 메모리 효율성을 높일 뿐만 아니라 최적화된 GPU 메모리 활용을 통해 효율성을 향상시키는 어텐션 알고리즘의 변형입니다.
+
+3. **아키텍처 혁신:** 추론 시 대규모 언어 모델은 주로 동일한 방식(긴 입력 맥락을 가진 자기회귀 텍스트 생성 방식)으로 배포되는데, 더 효율적인 추론을 가능하게 하는 특화된 모델 아키텍처가 제안되었습니다. 이러한 모델 아키텍처의 가장 중요한 발전으로는 [Alibi](https://arxiv.org/abs/2108.12409), [Rotary embeddings](https://arxiv.org/abs/2104.09864), [Multi-Query Attention (MQA)](https://arxiv.org/abs/1911.02150), [Grouped-Query-Attention (GQA)]((https://arxiv.org/abs/2305.13245))이 있습니다.
+
+이 가이드에서는 텐서의 관점에서 자기회귀 생성에 대한 분석을 제공합니다. 낮은 정밀도를 채택하는 것의 장단점을 논의하고, 최신 어텐션 알고리즘을 포괄적으로 탐구하며, 향상된 대규모 언어 모델 아키텍처에 대해 논합니다. 이 과정에서 각 기능의 개선 사항을 보여주는 실용적인 예제를 확인합니다.
+
+## 1. 낮은 정밀도 [[1-lower-precision]]
+
+대규모 언어 모델을 가중치 행렬과 벡터의 집합으로 보고, 텍스트 입력을 벡터의 시퀀스로 본다면, 대규모 언어 모델의 메모리 요구사항을 가장 잘 이해할 수 있습니다. 이어지는 내용에서 *가중치*는 모델의 모든 가중치 행렬과 벡터를 의미합니다.
+
+이 가이드를 작성하는 시점의 대규모 언어 모델은 최소 몇십억 개의 매개변수로 구성되어 있습니다. 각 매개변수는 `4.5689`와 같은 십진수로 이루어져 있으며, 보통 [float32](https://en.wikipedia.org/wiki/Single-precision_floating-point_format), [bfloat16](https://en.wikipedia.org/wiki/Bfloat16_floating-point_format) 또는 [float16](https://en.wikipedia.org/wiki/Half-precision_floating-point_format) 형식으로 저장됩니다. 이를 통해 대규모 언어 모델을 메모리에 로드하는 데 필요한 메모리의 요구사항을 쉽게 계산할 수 있습니다:
+
+> *X * 10억 개의 매개변수를 가진 모델의 가중치를 로드하려면 float32 정밀도에서 대략 4 * X GB의 VRAM이 필요합니다.*
+
+요즘에는 모델이 float32 정밀도로 훈련되는 경우는 드물고, 일반적으로 bfloat16 정밀도나 가끔 float16 정밀도로 훈련됩니다. 따라서 경험적으로 알아낸 법칙은 다음과 같습니다:
+
+> *X * 10억 개의 매개변수를 가진 모델의 가중치를 로드하려면 bfloat16/float16 정밀도에서 대략 2 * X GB의 VRAM이 필요합니다.*
+
+짧은 텍스트 입력(1024 토큰 미만)의 경우, 추론을 위한 메모리 요구 사항의 대부분은 가중치를 로드하는 데 필요한 메모리 요구 사항입니다. 따라서 지금은 추론을 위한 메모리 요구 사항이 모델의 가중치를 GPU VRAM에 로드하는 데 필요한 메모리 요구 사항과 같다고 가정합시다.
+
+모델을 bfloat16으로 로드하는 데 대략 얼마나 많은 VRAM이 필요한지 몇 가지 예를 들어보겠습니다:
+
+- **GPT3**는 2 \* 175 GB = **350 GB** VRAM이 필요합니다.
+- [**Bloom**](https://huggingface.co/bigscience/bloom)은 2 \* 176 GB = **352 GB** VRAM이 필요합니다.
+- [**Llama-2-70b**](https://huggingface.co/meta-llama/Llama-2-70b-hf)는 2 \* 70 GB = **140 GB** VRAM이 필요합니다.
+- [**Falcon-40b**](https://huggingface.co/tiiuae/falcon-40b)는 2 \* 40 GB = **80 GB** VRAM이 필요합니다.
+- [**MPT-30b**](https://huggingface.co/mosaicml/mpt-30b)는 2 * 30 GB = **60 GB** VRAM이 필요합니다.
+- [**bigcode/starcoder**](https://huggingface.co/bigcode/starcoder)는 2 * 15.5 GB = **31 GB** VRAM이 필요합니다.
+
+이 문서를 작성하는 시점에서, 현재 시장에서 가장 큰 GPU 칩은 80GB의 VRAM을 제공하는 A100과 H100입니다. 앞서 언급된 대부분의 모델들은 로드하기 위해서는 최소 80GB 이상의 용량을 필요로 하며, 따라서 [텐서 병렬 처리](https://huggingface.co/docs/transformers/perf_train_gpu_many#tensor-parallelism) 및/또는 [파이프라인 병렬 처리](https://huggingface.co/docs/transformers/perf_train_gpu_many#naive-model-parallelism-vertical-and-pipeline-parallelism)를 반드시 필요로 합니다.
+
+🤗 Transformers는 텐서 병렬 처리를 바로 지원하지 않습니다. 이는 모델 아키텍처가 특정 방식으로 작성되어야 하기 때문입니다. 텐서 병렬 처리를 지원하는 방식으로 모델을 작성하는 데 관심이 있다면 [the text-generation-inference library](https://github.com/huggingface/text-generation-inference/tree/main/server/text_generation_server/models/custom_modeling)를 참조해 보시기 바랍니다.
+
+기본적인 파이프라인 병렬 처리는 바로 지원됩니다. 이를 위해 단순히 모델을 `device="auto"`로 로드하면 [여기](https://huggingface.co/docs/accelerate/v0.22.0/en/concept_guides/big_model_inference)에 설명된 대로 사용 가능한 GPU에 모델의 서로 다른 레이어를 자동으로 배치합니다. 이것은 매우 효과적이긴 하지만 이러한 기본 파이프라인 병렬 처리는 GPU 유휴 문제를 해결하지 못한다는 점을 유의해야 합니다. 더 발전된 파이프라인 병렬 처리가 필요하며, 이에 대한 설명은 [여기](https://huggingface.co/docs/transformers/en/perf_train_gpu_many#naive-model-parallelism-vertical-and-pipeline-parallelism)에서 확인할 수 있습니다.
+
+80GB A100 GPU 8개를 가진 노드에 접근할 수 있다면, BLOOM을 다음과 같이 로드할 수 있습니다.
+
+```bash
+!pip install transformers accelerate bitsandbytes optimum
+```
+```python
+from transformers import AutoModelForCausalLM
+
+model = AutoModelForCausalLM.from_pretrained("bigscience/bloom", device_map="auto", pad_token_id=0)
+```
+
+`device_map="auto"`를 사용하면 모든 사용 가능한 GPU에 어텐션 레이어가 고르게 분산됩니다.
+
+이 가이드에서는 [bigcode/octocoder](https://huggingface.co/bigcode/octocoder)를 사용할 것입니다. 이 모델은 단일 40GB A100 GPU 장치에서 실행할 수 있습니다. 앞으로 적용할 모든 메모리 및 속도 최적화는 모델 또는 텐서 병렬 처리를 필요로 하는 다른 모델에도 동일하게 적용될 수 있습니다.
+
+모델이 bfloat16 정밀도로 로드되기 때문에, 위의 경험적으로 알아낸 법칙을 사용하면 `bigcode/octocoder`를 사용하여 추론을 실행하기 위한 메모리 요구 사항이 약 31GB VRAM일 것으로 예상됩니다. 한 번 시도해 보겠습니다.
+
+먼저 모델과 토크나이저를 로드한 다음, 둘 다 Transformers의 [파이프라인](https://huggingface.co/docs/transformers/main_classes/pipelines) 객체에 전달합니다.
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer, pipeline
+import torch
+
+model = AutoModelForCausalLM.from_pretrained("bigcode/octocoder", torch_dtype=torch.bfloat16, device_map="auto", pad_token_id=0)
+tokenizer = AutoTokenizer.from_pretrained("bigcode/octocoder")
+
+pipe = pipeline("text-generation", model=model, tokenizer=tokenizer)
+```
+
+```python
+prompt = "Question: Please write a function in Python that transforms bytes to Giga bytes.\n\nAnswer:"
+
+result = pipe(prompt, max_new_tokens=60)[0]["generated_text"][len(prompt):]
+result
+```
+
+**출력**:
+```
+Here is a Python function that transforms bytes to Giga bytes:\n\n```python\ndef bytes_to_giga_bytes(bytes):\n return bytes / 1024 / 1024 / 1024\n```\n\nThis function takes a single
+```
+
+좋습니다. 이제 결과를 직접 사용하여 바이트를 기가바이트로 변환할 수 있습니다.
+
+```python
+def bytes_to_giga_bytes(bytes):
+ return bytes / 1024 / 1024 / 1024
+```
+
+[`torch.cuda.max_memory_allocated`](https://pytorch.org/docs/stable/generated/torch.cuda.max_memory_allocated.html)를 호출하여 최대 GPU 메모리 할당을 측정해 보겠습니다.
+
+```python
+bytes_to_giga_bytes(torch.cuda.max_memory_allocated())
+```
+
+**출력**:
+```bash
+29.0260648727417
+```
+
+대략적으로 계산한 결과와 거의 일치합니다! 바이트에서 킬로바이트로 변환할 때 1000이 아닌 1024로 곱해야 하므로 숫자가 정확하지 않은 것을 알 수 있습니다. 따라서 대략적으로 계산할 때 공식은 "최대 X GB"으로 이해할 수 있습니다. 만약 우리가 모델을 float32 정밀도로 실행하려고 했다면 더 큰 크기인 64GB의 VRAM이 필요했을 것입니다.
+
+> 거의 모든 모델이 요즘 bfloat16으로 학습되므로, [GPU가 bfloat16을 지원](https://discuss.pytorch.org/t/bfloat16-native-support/117155/5)한다면 모델을 float32 정밀도로 실행할 이유가 없습니다. float32로 돌리는 모델은 학습할 때 사용했던 정밀도보다 더 나은 추론 결과를 제공하지 않습니다.
+
+모델 가중치가 어떤 정밀도 형식으로 Hub에 저장되어 있는지 확실하지 않은 경우, HuggingFace Hub에서 해당 체크포인트 config의 `"torch_dtype"`을 확인하면 됩니다, *예*를 들어 [여기](https://huggingface.co/meta-llama/Llama-2-7b-hf/blob/6fdf2e60f86ff2481f2241aaee459f85b5b0bbb9/config.json#L21)를 확인하세요. 모델을 `from_pretrained(..., torch_dtype=...)`로 로드할 때는 config에 명시된 정밀도 유형과 동일한 정밀도로 설정하는 것이 권장됩니다. 단, 원래 유형이 float32인 경우 추론을 위해 `float16` 또는 `bfloat16`을 둘 다 사용할 수 있습니다.
+
+이제 `flush(...)` 함수를 정의하여 모든 메모리를 해제하고, GPU 메모리의 최대 할당량을 정확하게 측정하도록 합시다.
+
+
+```python
+del pipe
+del model
+
+import gc
+import torch
+
+def flush():
+ gc.collect()
+ torch.cuda.empty_cache()
+ torch.cuda.reset_peak_memory_stats()
+```
+
+다음 실험을 위해 바로 호출해 봅시다.
+
+```python
+flush()
+```
+최근 버전의 accelerate 라이브러리에서는 `release_memory()`라는 유틸리티 메소드도 사용할 수 있습니다.
+
+```python
+from accelerate.utils import release_memory
+# ...
+
+release_memory(model)
+```
+
+만약 GPU에 32GB의 VRAM이 없다면 어떻게 될까요? 모델 가중치를 성능에 큰 손실 없이 8비트 또는 4비트로 양자화할 수 있다는 것이 밝혀졌습니다(참고: [Dettmers et al.](https://arxiv.org/abs/2208.07339)). 최근의 [GPTQ 논문](https://arxiv.org/abs/2210.17323) 에서는 모델을 3비트 또는 2비트로 양자화해도 성능 손실이 허용 가능한 수준임을 보여주었습니다🤯.
+
+너무 자세한 내용은 다루지 않고 설명하자면, 양자화는 가중치의 정밀도를 줄이면서 모델의 추론 결과를 가능한 한 정확하게(즉, bfloat16과 최대한 가깝게) 유지하려고 합니다. 양자화는 특히 텍스트 생성에 잘 작동하는데, 이는 우리가 *가장 가능성 있는 다음 토큰 집합*을 선택하는 것에 초점을 두고 있기 때문이며, 다음 토큰의 *logit* 분포값을 정확하게 예측할 필요는 없기 때문입니다. 핵심은 다음 토큰 *logit* 분포가 대략적으로 동일하게 유지되어 `argmax` 또는 `topk` 연산이 동일한 결과를 제공하는 것입니다.
+
+다양한 양자화 기법이 존재하지만, 자세히 다루지는 않을 것입니다. 일반적으로 모든 양자화 기법은 다음과 같이 작동합니다:
+
+- 1. 모든 가중치를 목표 정밀도로 양자화합니다.
+- 2. 양자화된 가중치를 로드하고, bfloat16 정밀도의 입력 벡터 시퀀스를 모델에 전달합니다.
+- 3. 가중치를 동적으로 bfloat16으로 반대로 양자화(dequantize)하여 입력 벡터와 함께 bfloat16 정밀도로 계산을 수행합니다.
+
+간단히 말해서, *입력-가중치 행렬* 곱셈은, \\( X \\)가 *입력*, \\( W \\)가 가중치 행렬, \\( Y \\)가 출력인 경우 다음과 같습니다:
+
+$$ Y = X * W $$
+
+위 공식이 다음과 같이 변경됩니다
+
+$$ Y = X * \text{dequantize}(W) $$
+
+모든 행렬 곱셈에 대해 위와 같이 수행됩니다. 입력이 네트워크 그래프를 통과하면서 모든 가중치 행렬에 대해 역양자화(dequantization)와 재양자화(re-quantization)가 순차적으로 수행됩니다.
+
+따라서, 양자화된 가중치를 사용할 때 추론 시간이 감소하지 **않고** 오히려 증가하는 경우가 많습니다. 이제 이론은 충분하니 실제로 시도해 봅시다! Transformers를 사용하여 가중치를 양자화하려면 [`bitsandbytes`](https://github.com/TimDettmers/bitsandbytes) 라이브러리가 설치되어 있는지 확인해야 합니다.
+
+```bash
+!pip install bitsandbytes
+```
+
+그런 다음 `from_pretrained`에 `load_in_8bit=True` 플래그를 추가하여 8비트 양자화로 모델을 로드할 수 있습니다.
+
+```python
+model = AutoModelForCausalLM.from_pretrained("bigcode/octocoder", load_in_8bit=True, pad_token_id=0)
+```
+
+이제 예제를 다시 실행하고 메모리 사용량을 측정해 봅시다.
+
+```python
+pipe = pipeline("text-generation", model=model, tokenizer=tokenizer)
+
+result = pipe(prompt, max_new_tokens=60)[0]["generated_text"][len(prompt):]
+result
+```
+
+**출력**:
+```
+Here is a Python function that transforms bytes to Giga bytes:\n\n```python\ndef bytes_to_giga_bytes(bytes):\n return bytes / 1024 / 1024 / 1024\n```\n\nThis function takes a single
+```
+
+좋습니다. 정확도 손실 없이 이전과 동일한 결과를 얻고 있습니다! 이번에는 사용된 메모리 양을 확인해 봅시다.
+
+```python
+bytes_to_giga_bytes(torch.cuda.max_memory_allocated())
+```
+
+**출력**:
+```
+15.219234466552734
+```
+
+훨씬 적네요! 메모리 사용량이 15GB를 조금 넘는 수준으로 줄어들어 4090과 같은 소비자용 GPU에서도 이 모델을 실행할 수 있습니다. 메모리 효율성에서 매우 큰 향상을 보이고 있으며 모델 출력의 품질 저하도 거의 없습니다. 그러나 추론 중에 약간의 속도 저하가 발생한 것을 확인할 수 있습니다.
+
+
+모델을 삭제하고 메모리를 다시 초기화합니다.
+
+```python
+del model
+del pipe
+```
+
+```python
+flush()
+```
+
+이제 4비트 양자화가 제공하는 최대 GPU 메모리 사용량을 확인해 봅시다. 4비트로 모델을 양자화하려면 이전과 동일한 API를 사용하되 이번에는 `load_in_8bit=True` 대신 `load_in_4bit=True`를 전달하면 됩니다.
+
+```python
+model = AutoModelForCausalLM.from_pretrained("bigcode/octocoder", load_in_4bit=True, low_cpu_mem_usage=True, pad_token_id=0)
+
+pipe = pipeline("text-generation", model=model, tokenizer=tokenizer)
+
+result = pipe(prompt, max_new_tokens=60)[0]["generated_text"][len(prompt):]
+result
+```
+
+**출력**:
+```
+Here is a Python function that transforms bytes to Giga bytes:\n\n```\ndef bytes_to_gigabytes(bytes):\n return bytes / 1024 / 1024 / 1024\n```\n\nThis function takes a single argument
+```
+
+바로 전 코드 스니펫에서 `python`만 누락되고, 이 전과 거의 동일한 출력 텍스트를 보고 있습니다. 이제 얼마나 많은 메모리가 필요했는지 확인해 봅시다.
+
+```python
+bytes_to_giga_bytes(torch.cuda.max_memory_allocated())
+```
+
+**출력**:
+```
+9.543574333190918
+```
+
+9.5GB밖에 되지 않습니다! 150억 개 이상의 파라미터를 가진 모델인 것을 감안하면 매우 적은 양입니다.
+
+여기서는 모델의 정확도 저하가 거의 없음을 확인할 수 있지만, 실제로는 4비트 양자화를 8비트 양자화나 `bfloat16`를 사용한 추론 결과와 비교하면 결과가 다를 수 있습니다. 사용자가 직접 시도해 보는 것이 좋겠습니다.
+
+또한 4비트 양자화에 사용된 더 공격적인 양자화 방법으로 인해 추론 시 \\( \text{quantize} \\)와 \\( \text{dequantize} \\) 과정이 더 오래 걸리므로 여기서도 8비트 양자화와 비교하여 추론 속도가 약간 느려졌음을 유의하세요.
+
+```python
+del model
+del pipe
+```
+```python
+flush()
+```
+
+전체적으로 OctoCoder를 8비트 정밀도로 실행하면 필요한 GPU VRAM이 32GB에서 15GB로 줄어들었고, 4비트 정밀도로 모델을 실행하면 필요한 GPU VRAM이 9GB로 더 줄어드는 것을 확인했습니다.
+
+4비트 양자화는 RTX3090, V100, T4와 같은 GPU에서 모델을 실행할 수 있게 해주며, 이는 대부분의 사람들이 접근할 수 있는 GPU입니다.
+
+양자화에 대한 더 많은 정보를 확인하고 4비트보다 더 적은 GPU VRAM 메모리로 모델을 양자화하거나, 더 많은 양자화 관련 정보를 보려면 [`AutoGPTQ`](https://huggingface.co/docs/transformers/main/en/main_classes/quantization#autogptq-integration%60) 구현을 참조하는 것을 추천합니다.
+
+> 결론적으로, 모델 양자화는 향상된 메모리 효율성과 모델 정확성 간의 균형을 맞추는 것이며, 경우에 따라 추론 시간에도 영향을 미칠 수 있습니다.
+
+실제 사례에서 GPU 메모리가 충분하다면, 양자화를 고려할 필요가 없습니다. 그러나 많은 GPU는 양자화 없이 대규모 언어 모델을 실행할 수 없으며, 이 경우 4비트 및 8비트 양자화가 매우 유용한 도구입니다.
+
+사용과 관련한 더 자세한 정보는 [트랜스포머 양자화 문서](https://huggingface.co/docs/transformers/main_classes/quantization#general-usage)를 참고하는 것을 강력히 추천합니다. 다음으로, 더 나은 알고리즘과 개선된 모델 아키텍처를 사용하여 계산 및 메모리 효율성을 향상시키는 방법을 살펴보겠습니다.
+
+## 2. 플래시 어텐션 [[2-flash-attention]]
+
+오늘날의 최고 성능을 자랑하는 대규모 언어 모델은 대체로 피드포워드 레이어(feed-forward layer), 활성화 레이어(activation layer), 레이어 정규화 레이어(layer normalization layer), 그리고 가장 중요한 셀프 어텐션 레이어(self-attention layer)로 구성된 아키텍처를 공유하고 있습니다.
+
+셀프 어텐션 레이어는 입력 토큰 간의 문맥적 관계를 이해할 수 있게 해 주기 때문에 대규모 언어 모델의 핵심 요소입니다.
+하지만 셀프 어텐션 레이어의 최대 GPU 메모리 소비는 입력 토큰의 수(이하 \\( N \\)으로 표기)와 함께 계산 및 메모리 복잡성이 *2차적*으로 증가합니다. 입력 시퀀스가 짧은 경우(최대 1000개)에는 크게 눈에 띄지 않지만, 더 긴 입력 시퀀스(약 16000개)에서는 심각한 문제가 됩니다.
+
+자세히 한 번 들여다 봅시다. 길이 \\( N \\)의 입력 \\( \mathbf{X} \\)에 대한 셀프 어텐션 레이어의 출력 \\( \mathbf{O} \\)을 계산하는 공식은 다음과 같습니다:
+
+$$ \textbf{O} = \text{Attn}(\mathbf{X}) = \mathbf{V} \times \text{Softmax}(\mathbf{QK}^T) \text{ with } \mathbf{Q} = \mathbf{W}_q \mathbf{X}, \mathbf{V} = \mathbf{W}_v \mathbf{X}, \mathbf{K} = \mathbf{W}_k \mathbf{X} $$
+
+\\( \mathbf{X} = (\mathbf{x}1, ... \mathbf{x}{N}) \\)는 어텐션 레이어의 입력 시퀀스입니다. 프로젝션 \\( \mathbf{Q} \\)와 \\( \mathbf{K} \\)는 각각 \\( N \\)개의 벡터로 구성되며, 그 결과 \\( \mathbf{QK}^T \\)의 크기는 \\( N^2 \\)가 됩니다.
+
+대규모 언어 모델은 일반적으로 여러 개의 어텐션 헤드를 가지고 있어 여러 개의 셀프 어텐션 계산을 병렬로 수행합니다. 대규모 언어 모델이 40개의 어텐션 헤드를 가지고 bfloat16 정밀도로 실행된다고 가정하면, \\( \mathbf{QK^T} \\) 행렬을 저장하는 데 필요한 메모리를 \\( 40 * 2 * N^2 \\) 바이트로 계산할 수 있습니다. \\( N=1000 \\)일 때는 약 50MB의 VRAM만 필요하지만, \\( N=16000 \\)일 때는 19GB의 VRAM이 필요하며, \\( N=100,000 \\)일 때는 \\( \mathbf{QK^T} \\) 행렬을 저장하기 위해 거의 1TB의 VRAM이 필요합니다.
+
+요약하자면, 기본 셀프 어텐션 알고리즘은 큰 입력 컨텍스트에 대해 매우 과도한 메모리 사용을 요구하게 됩니다.
+
+대규모 언어 모델의 텍스트 이해 및 생성 능력이 개선되면서 점점 더 복잡한 작업에 사용되고 있습니다. 한때 몇 문장의 번역이나 요약을 처리하던 모델이 이제는 전체 페이지를 처리해야 하게 되면서 광범위한 입력 길이를 처리할 수 있는 능력이 요구되고 있습니다.
+
+어떻게 하면 큰 입력 길이에 대한 과도한 메모리 요구를 없앨 수 있을까요? \\( QK^T \\) 행렬을 제거하는 새로운 셀프 어텐션 메커니즘을 계산하는 방법이 필요합니다. [Tri Dao et al.](https://arxiv.org/abs/2205.14135)은 바로 이러한 새로운 알고리즘을 개발하였고, 그것이 **플래시 어텐션(Flash Attention)**입니다.
+
+간단히 말해, 플래시 어텐션은 \\(\mathbf{V} \times \text{Softmax}(\mathbf{QK}^T\\)) 계산을 분할하는데, 여러 번의 소프트맥스 계산을 반복하면서 작은 청크 단위로 출력을 계산합니다:
+
+$$ \textbf{O}_i \leftarrow s^a_{ij} * \textbf{O}_i + s^b_{ij} * \mathbf{V}_{j} \times \text{Softmax}(\mathbf{QK}^T_{i,j}) \text{ for multiple } i, j \text{ iterations} $$
+
+여기서 \\( s^a_{ij} \\)와 \\( s^b_{ij} \\)는 각 \\( i \\)와 \\( j \\)에 대해 계산되는 소프트맥스 정규화 통계량입니다.
+
+플래시 어텐션의 전체 알고리즘은 더 복잡하며, 본 가이드의 범위를 벗어나기 때문에 크게 단순화하였습니다. 여러분은 잘 작성된 [Flash Attention paper](https://arxiv.org/abs/2205.14135) 논문을 참조하여 더 자세한 내용을 확인해 보시기 바랍니다.
+
+주요 요점은 다음과 같습니다:
+
+> 소프트맥스 정규화 통계량과 몇 가지 스마트한 수학적 방법을 사용함으로써, 플래시 어텐션은 기본 셀프 어텐션 레이어와 **숫자적으로 동일한** 출력을 제공하고 메모리 비용은 \\( N \\)에 따라 선형적으로만 증가합니다.
+
+공식을 보면, 플래시 어텐션이 더 많은 계산을 필요로 하기 때문에 기본 셀프 어텐션 공식보다 훨씬 느릴 것이라고 생각할 수 있습니다. 실제로 플래시 어텐션은 소프트맥스 정규화 통계량을 지속적으로 다시 계산해야 하기 때문에 일반 어텐션보다 더 많은 FLOP이 필요합니다. (더 자세한 내용은 [논문](https://arxiv.org/abs/2205.14135)을 참조하세요)
+
+> 그러나 플래시 어텐션은 기본 어텐션보다 추론 속도가 훨씬 빠릅니다. 이는 GPU의 느리고 고대역폭 메모리(VRAM)의 사용량을 크게 줄이고 대신 빠른 온칩 메모리(SRAM)에 집중할 수 있기 때문입니다.
+
+본질적으로, 플래시 어텐션의 모든 중간 단계의 쓰기 및 읽기 작업은 느린 VRAM 메모리에 접근하지 않고 빠른 *온칩* SRAM 메모리를 사용하여 출력 벡터 \\( \mathbf{O} \\)를 계산할 수 있도록 합니다.
+
+현실적으로 플래시 어텐션이 사용 가능한 경우 이를 **사용하지 않을** 이유는 전혀 없습니다. 이 알고리즘은 수학적으로 동일한 출력을 제공하며, 더 빠르고 메모리 효율적입니다.
+
+실제 예를 살펴보겠습니다.
+
+우리의 OctoCoder 모델은 이제 *시스템 프롬프트*가 포함된 훨씬 더 긴 입력 프롬프트를 받게 됩니다. 시스템 프롬프트는 대규모 언어 모델을 사용자의 작업에 맞춘 더 나은 어시스턴트로 유도하는 데 사용됩니다. 다음 예제에서는 OctoCoder를 더 나은 코딩 어시스턴트로 만들기 위한 시스템 프롬프트를 사용합니다.
+
+```python
+system_prompt = """Below are a series of dialogues between various people and an AI technical assistant.
+The assistant tries to be helpful, polite, honest, sophisticated, emotionally aware, and humble but knowledgeable.
+The assistant is happy to help with code questions and will do their best to understand exactly what is needed.
+It also tries to avoid giving false or misleading information, and it caveats when it isn't entirely sure about the right answer.
+That said, the assistant is practical really does its best, and doesn't let caution get too much in the way of being useful.
+
+The Starcoder models are a series of 15.5B parameter models trained on 80+ programming languages from The Stack (v1.2) (excluding opt-out requests).
+The model uses Multi Query Attention, was trained using the Fill-in-the-Middle objective, and with 8,192 tokens context window for a trillion tokens of heavily deduplicated data.
+
+-----
+
+Question: Write a function that takes two lists and returns a list that has alternating elements from each input list.
+
+Answer: Sure. Here is a function that does that.
+
+def alternating(list1, list2):
+ results = []
+ for i in range(len(list1)):
+ results.append(list1[i])
+ results.append(list2[i])
+ return results
+
+Question: Can you write some test cases for this function?
+
+Answer: Sure, here are some tests.
+
+assert alternating([10, 20, 30], [1, 2, 3]) == [10, 1, 20, 2, 30, 3]
+assert alternating([True, False], [4, 5]) == [True, 4, False, 5]
+assert alternating([], []) == []
+
+Question: Modify the function so that it returns all input elements when the lists have uneven length. The elements from the longer list should be at the end.
+
+Answer: Here is the modified function.
+
+def alternating(list1, list2):
+ results = []
+ for i in range(min(len(list1), len(list2))):
+ results.append(list1[i])
+ results.append(list2[i])
+ if len(list1) > len(list2):
+ results.extend(list1[i+1:])
+ else:
+ results.extend(list2[i+1:])
+ return results
+
+-----
+"""
+```
+시연을 위해 시스템 프롬프트를 10번 중복하여 증가시켜 플래시 어텐션의 메모리 절약 효과를 관찰할 수 있을 만큼 입력 길이를 충분히 길게 만듭니다. 원래의 텍스트 프롬프트를 다음과 같이 추가합니다. `"Question: Please write a function in Python that transforms bytes to Giga bytes.\n\nAnswer: Here"`
+
+```python
+long_prompt = 10 * system_prompt + prompt
+```
+
+모델을 다시 bfloat16 정밀도로 인스턴스화합니다.
+
+```python
+model = AutoModelForCausalLM.from_pretrained("bigcode/octocoder", torch_dtype=torch.bfloat16, device_map="auto")
+tokenizer = AutoTokenizer.from_pretrained("bigcode/octocoder")
+
+pipe = pipeline("text-generation", model=model, tokenizer=tokenizer)
+```
+
+이제 플래시 어텐션을 *사용하지 않고* 이전과 동일하게 모델을 실행하여 최대 GPU 메모리 요구량과 추론 시간을 측정해 봅시다.
+
+```python
+import time
+
+start_time = time.time()
+result = pipe(long_prompt, max_new_tokens=60)[0]["generated_text"][len(long_prompt):]
+
+print(f"Generated in {time.time() - start_time} seconds.")
+result
+```
+
+**출력**:
+```
+Generated in 10.96854019165039 seconds.
+Sure. Here is a function that does that.\n\ndef bytes_to_giga(bytes):\n return bytes / 1024 / 1024 / 1024\n\nAnswer: Sure. Here is a function that does that.\n\ndef
+````
+
+이전과 동일한 출력을 얻고 있지만, 이번에는 모델이 답변을 여러 번 반복하여 60개의 토큰이 잘릴 때까지 계속됩니다. 시연을 위해 시스템 프롬프트를 10번 반복했기 때문에 모델이 스스로 반복하도록 유도한 결과입니다. 이는 놀라운 일이 아닙니다.
+
+**참고** 실제 응용에서는 시스템 프롬프트를 10번 반복할 필요가 없습니다. 한 번만 사용하면 충분합니다!
+
+최대 GPU 메모리 요구량을 측정해 봅시다.
+
+```python
+bytes_to_giga_bytes(torch.cuda.max_memory_allocated())
+```
+
+**출력**:
+```bash
+37.668193340301514
+```
+
+보시다시피 최대 GPU 메모리 요구량이 처음보다 상당히 높아졌습니다. 이는 주로 입력 시퀀스가 길어졌기 때문입니다. 또한 생성 시간이 이제 1분을 넘어갑니다.
+
+다음 실험을 위해 `flush()`를 호출하여 GPU 메모리를 초기화합니다.
+
+```python
+flush()
+```
+
+비교를 위해, 동일한 기능을 실행하되 플래시 어텐션을 활성화해 보겠습니다.
+이를 위해 모델을 [BetterTransformer](https://huggingface.co/docs/optimum/bettertransformer/overview)로 변환하고, 이를 통해 PyTorch의 [SDPA self-attention](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention)을 활성화하면 플래시 어텐션을 사용할 수 있습니다.
+
+```python
+model.to_bettertransformer()
+```
+
+이제 이전과 동일한 코드 스니펫을 실행하면, 내부적으로 Transformers가 플래시 어텐션을 사용할 것입니다.
+
+```py
+start_time = time.time()
+with torch.backends.cuda.sdp_kernel(enable_flash=True, enable_math=False, enable_mem_efficient=False):
+ result = pipe(long_prompt, max_new_tokens=60)[0]["generated_text"][len(long_prompt):]
+
+print(f"Generated in {time.time() - start_time} seconds.")
+result
+```
+
+**출력**:
+```
+Generated in 3.0211617946624756 seconds.
+ Sure. Here is a function that does that.\n\ndef bytes_to_giga(bytes):\n return bytes / 1024 / 1024 / 1024\n\nAnswer: Sure. Here is a function that does that.\n\ndef
+```
+
+이전과 동일한 결과를 얻었지만, 플래시 어텐션 덕분에 매우 큰 속도 향상을 관찰할 수 있습니다.
+
+메모리 소비량을 마지막으로 한 번 더 측정해 봅시다.
+
+```python
+bytes_to_giga_bytes(torch.cuda.max_memory_allocated())
+```
+
+**출력**:
+```
+32.617331981658936
+```
+
+그리고 우리는 처음에 보았던 GPU 메모리 요구량인 29GB로 돌아왔습니다.
+
+플래시 어텐션을 사용하여 매우 긴 입력 시퀀스를 전달할 때 처음에 짧은 입력 시퀀스를 전달했을 때와 비교하여 약 100MB 정도의 GPU 메모리를 더 사용한다는 것을 관찰할 수 있습니다.
+
+```py
+flush()
+```
+
+플래시 어텐션 사용에 대한 자세한 정보는 [이 문서 페이지](https://huggingface.co/docs/transformers/en/perf_infer_gpu_one#flashattention-2)를 참조해 주세요.
+
+## 3. 아키텍처 혁신 [[3-architectural-innovations]]
+
+지금까지 우리는 계산 및 메모리 효율성을 개선하기 위해 다음을 살펴보았습니다:
+
+- 가중치를 낮은 정밀도 형식으로 변환
+- 셀프 어텐션 알고리즘을 보다 더 메모리 및 계산 효율적인 버전으로 교체
+
+이제 긴 텍스트 입력이 필요한 작업에 가장 효과적이고 효율적인 대규모 언어 모델 아키텍처로 변경하는 방법을 살펴보겠습니다. 작업의 예시는 다음과 같습니다:
+- 검색 증강 질의 응답
+- 요약
+- 채팅
+
+*채팅*을 위해서는 대규모 언어 모델이 긴 텍스트 입력을 처리하는 것뿐만 아니라 사용자와 어시스턴트 간의 대화도 효율적으로 처리할 수 있어야 합니다(예: ChatGPT).
+
+한번 학습된 후에는 대규모 언어 모델의 기본 아키텍처를 변경하기 어렵기 때문에, 대규모 언어 모델의 작업에 대한 고려를 미리 하고 이에 따라 모델의 아키텍처를 최적화하는 것이 중요합니다. 긴 입력 시퀀스에 대해 메모리 또는 성능의 병목 현상을 빠르게 발생시키는 모델 아키텍처의 중요한 두 가지 구성 요소가 있습니다.
+
+- 위치 임베딩
+- 키-값 캐시
+
+각 구성 요소를 더 자세히 살펴보겠습니다.
+
+### 3.1 대규모 언어 모델의 위치 임베딩 개선 [[31-improving-positional-embeddings-of-llms]]
+
+셀프 어텐션은 각 토큰을 서로의 토큰과 연관시킵니다.
+예를 들어, 텍스트 입력 시퀀스 *"Hello", "I", "love", "you"*의 \\( \text{Softmax}(\mathbf{QK}^T) \\) 행렬은 다음과 같을 수 있습니다:
+
+
+
+각 단어 토큰은 다른 모든 단어 토큰에 주의를 기울이는 확률 질량을 부여받아 모든 다른 단어 토큰과 관계를 맺게 됩니다. 예를 들어, 단어 *"love"*는 단어 *"Hello"*에 5%, *"I"*에 30%, 그리고 자신에게 65%의 주의를 기울입니다.
+
+셀프 어텐션 기반 대규모 언어 모델이 위치 임베딩이 없는 경우 텍스트 입력의 위치를 이해하는 데 큰 어려움을 겪을 것입니다. 이는 \\( \mathbf{QK}^T \\)에 의해 계산된 확률 점수가 상대적 위치 거리에 상관없이 각 단어 토큰을 다른 모든 단어 토큰과 \\( O(1) \\) 계산으로 연관시키기 때문입니다. 따라서 위치 임베딩이 없는 대규모 언어 모델은 각 토큰이 다른 모든 토큰과 동일한 거리에 있는 것으로 나타나기 때문에, *"Hello I love you"*와 *"You love I hello"*를 구분하는 것이 매우 어렵습니다.
+
+대규모 언어 모델이 문장의 순서를 이해하려면 추가적인 *단서*가 필요하며, 이는 일반적으로 *위치 인코딩* (또는 *위치 임베딩*이라고도 함)의 형태로 적용됩니다.
+위치 인코딩은 각 토큰의 위치를 숫자 표현으로 인코딩하여 대규모 언어 모델이 문장의 순서를 더 잘 이해할 수 있도록 도와줍니다.
+
+[*Attention Is All You Need*](https://arxiv.org/abs/1706.03762) 논문의 저자들은 사인 함수 기반의 위치 임베딩 \\( \mathbf{P} = \mathbf{p}_1, \ldots, \mathbf{p}_N \\)을 도입했습니다. 각 벡터 \\( \mathbf{p}_i \\)는 위치 \\( i \\)의 사인 함수로 계산됩니다. 위치 인코딩은 입력 시퀀스 벡터에 단순히 더해져 \\( \mathbf{\hat{X}} = \mathbf{\hat{x}}_1, \ldots, \mathbf{\hat{x}}_N \\) = \\( \mathbf{x}_1 + \mathbf{p}_1, \ldots, \mathbf{x}_N + \mathbf{p}_N \\) 모델이 문장 순서를 더 잘 학습할 수 있도록 합니다.
+
+고정된 위치 임베딩 대신 [Devlin et al.](https://arxiv.org/abs/1810.04805)과 같은 다른 연구자들은 학습된 위치 인코딩을 사용했습니다. 이 경우 위치 임베딩 \\( \mathbf{P} \\)은 학습 중에 사용됩니다.
+
+사인 함수 및 학습된 위치 임베딩은 문장 순서를 대규모 언어 모델에 인코딩하는 주요 방법이었지만, 이러한 위치 인코딩과 관련된 몇 가지 문제가 발견되었습니다:
+
+ 1. 사인 함수와 학습된 위치 임베딩은 모두 절대 위치 임베딩으로, 각 위치 ID \\( 0, \ldots, N \\)에 대해 고유한 임베딩을 인코딩합니다. [Huang et al.](https://arxiv.org/abs/2009.13658) 및 [Su et al.](https://arxiv.org/abs/2104.09864)의 연구에 따르면, 절대 위치 임베딩은 긴 텍스트 입력에 대해 대규모 언어 모델 성능이 저하됩니다. 긴 텍스트 입력의 경우, 모델이 절대 위치 대신 입력 토큰 간의 상대적 위치 거리를 학습하는 것이 유리합니다.
+ 2. 학습된 위치 임베딩을 사용할 때, 대규모 언어 모델은 고정된 입력 길이 \\( N \\)으로 학습되어야 하므로, 학습된 입력 길이보다 더 긴 입력 길이에 대해 추론하는 것이 어렵습니다.
+
+최근에는 위에서 언급한 문제를 해결할 수 있는 상대적 위치 임베딩이 더 인기를 끌고 있습니다. 특히 다음과 같은 방법들이 주목받고 있습니다:
+
+- [Rotary Position Embedding (RoPE)](https://arxiv.org/abs/2104.09864)
+- [ALiBi](https://arxiv.org/abs/2108.12409)
+
+*RoPE*와 *ALiBi*는 모두 셀프 어텐션 알고리즘 내에서 직접적으로 문장 순서를 모델에게 알려주는 것이 최선이라고 주장합니다. 이는 단어 토큰이 서로 관계를 맺는 곳이기 때문입니다. 구체적으로, 문장 순서를 \\( \mathbf{QK}^T \\) 계산을 수정하는 방식으로 알려주어야 한다는 것입니다.
+
+너무 많은 세부 사항을 다루지 않고, *RoPE*는 위치 정보를 쿼리-키 쌍에 인코딩할 수 있다고 지적합니다. 예를 들어, 각 벡터 \\( \mathbf{q}_i \\)와 \\( \mathbf{x}_j \\)를 각각 \\( \theta * i \\)와 \\( \theta * j \\)의 각도로 회전시킴으로써 다음과 같이 표현할 수 있습니다:
+
+$$ \mathbf{\hat{q}}_i^T \mathbf{\hat{x}}_j = \mathbf{{q}}_i^T \mathbf{R}_{\theta, i -j} \mathbf{{x}}_j. $$
+
+여기서 \\( \mathbf{R}_{\theta, i - j} \\)는 회전 행렬을 나타냅니다. \\( \theta \\)는 훈련 중에 *학습되지 않으며*, 대신 학습 중 최대 입력 시퀀스 길이에 따라 사전 정의된 값으로 설정됩니다.
+
+> 이렇게 함으로써 \\( \mathbf{q}_i \\)와 \\( \mathbf{q}_j \\) 간의 확률 점수는 \\( i \ne j \\)인 경우에만 영향을 받으며, 각 벡터의 특정 위치 \\( i \\)와 \\( j \\)와는 상관없이 오직 상대적 거리 \\( i - j \\)에만 의존하게 됩니다.
+
+*RoPE*는 현재 여러 중요한 대규모 언어 모델이 사용되고 있습니다. 예를 들면:
+
+- [**Falcon**](https://huggingface.co/tiiuae/falcon-40b)
+- [**Llama**](https://arxiv.org/abs/2302.13971)
+- [**PaLM**](https://arxiv.org/abs/2204.02311)
+
+대안으로, *ALiBi*는 훨씬 더 간단한 상대적 위치 인코딩 방식을 제안합니다. 입력 토큰 간의 상대적 거리를 음수인 정수로서 사전 정의된 값 `m`으로 스케일링하여 \\( \mathbf{QK}^T \\) 행렬의 각 쿼리-키 항목에 소프트맥스 계산 직전에 추가합니다.
+
+
+
+[ALiBi](https://arxiv.org/abs/2108.12409) 논문에서 보여주듯이, 이 간단한 상대적 위치 인코딩은 매우 긴 텍스트 입력 시퀀스에서도 모델이 높은 성능을 유지할 수 있게 합니다.
+
+*ALiBi*는 현재 여러 중요한 대규모 언어 모델 모델이 사용하고 있습니다. 예를 들면:
+
+- [**MPT**](https://huggingface.co/mosaicml/mpt-30b)
+- [**BLOOM**](https://huggingface.co/bigscience/bloom)
+
+*RoPE*와 *ALiBi* 위치 인코딩은 모두 학습 중에 보지 못한 입력 길이에 대해 확장할 수 있으며, *ALiBi*가 *RoPE*보다 더 잘 확장되는 것으로 나타났습니다. *ALiBi*의 경우, 하삼각 위치 행렬의 값을 입력 시퀀스 길이에 맞추어 증가시키기만 하면 됩니다. *RoPE*의 경우, 학습 중에 사용된 동일한 \\( \theta \\)를 유지하면 학습 중에 보지 못한 매우 긴 텍스트 입력을 전달할 때 성능이 저하됩니다(참고: [Press et al.](https://arxiv.org/abs/2108.12409)). 그러나 커뮤니티는 \\( \theta \\)를 조정하는 몇 가지 효과적인 트릭을 찾아냈으며, 이를 통해 *RoPE* 위치 임베딩이 확장된 텍스트 입력 시퀀스에서도 잘 작동할 수 있게 되었습니다(참고: [here](https://github.com/huggingface/transformers/pull/24653)).
+
+> RoPE와 ALiBi는 모두 훈련 중에 *학습되지 않는* 상대적 위치 임베딩으로 다음과 같은 직관에 기반합니다:
+ - 텍스트 입력에 대한 위치 단서는 셀프 어텐션 레이어의 \\( QK^T \\) 행렬에 직접 제공되어야 합니다.
+ - 대규모 언어 모델은 일정한 *상대적* 거리 위치 인코딩을 서로 학습하도록 유도되어야 합니다.
+ - 텍스트 입력 토큰 간의 거리가 멀어질수록, 그들의 쿼리-값 확률은 낮아져야 합니다. RoPE와 ALiBi는 서로 멀리 떨어진 토큰의 쿼리-키 확률을 낮춥니다. RoPE는 쿼리-키 벡터 간의 각도를 증가시켜 벡터 곱을 감소시키는 방식으로, ALiBi는 벡터 곱에 큰 음수를 추가하는 방식으로 이 작업을 수행합니다.
+
+결론적으로, 큰 텍스트 입력을 처리해야 하는 작업에 배포될 예정인 대규모 언어 모델은 RoPE와 ALiBi와 같은 상대적 위치 임베딩으로 훈련하는 것이 더 좋습니다. 또한 RoPE와 ALiBi를 사용하여 훈련된 대규모 언어 모델이 고정 길이 \\( N_1 = 2048 \\)에서만 훈련되었더라도 위치 임베딩을 외삽하여 \\( N_1 \\)보다 훨씬 큰 텍스트 입력 \\( N_2 = 8192 > N_1 \\)로 실습에서 사용할 수 있음을 유의하세요.
+
+### 3.2 키-값 캐시 [[32-the-key-value-cache]]
+
+대규모 언어 모델을 이용한 자기회귀 텍스트 생성은 입력 시퀀스를 반복적으로 넣고, 다음 토큰을 샘플링하며, 그 다음 토큰을 입력 시퀀스에 추가하고, 대규모 언어 모델이 생성을 완료했다는 토큰을 생성할 때까지 이를 계속 수행하는 방식으로 작동합니다.
+
+자기회귀 생성이 어떻게 작동하는지에 대한 시각적 설명을 보려면 [Transformer's Generate Text Tutorial](https://huggingface.co/docs/transformers/llm_tutorial#generate-text)을 참조하세요.
+
+자기회귀 생성이 실제로 어떻게 작동하는지 보여주는 간단한 코드 스니펫을 실행해 보겠습니다. 여기서는 `torch.argmax`를 통해 가장 가능성이 높은 다음 토큰을 가져올 것입니다.
+
+```python
+input_ids = tokenizer(prompt, return_tensors="pt")["input_ids"].to("cuda")
+
+for _ in range(5):
+ next_logits = model(input_ids)["logits"][:, -1:]
+ next_token_id = torch.argmax(next_logits,dim=-1)
+
+ input_ids = torch.cat([input_ids, next_token_id], dim=-1)
+ print("shape of input_ids", input_ids.shape)
+
+generated_text = tokenizer.batch_decode(input_ids[:, -5:])
+generated_text
+```
+
+**출력**:
+```
+shape of input_ids torch.Size([1, 21])
+shape of input_ids torch.Size([1, 22])
+shape of input_ids torch.Size([1, 23])
+shape of input_ids torch.Size([1, 24])
+shape of input_ids torch.Size([1, 25])
+[' Here is a Python function']
+```
+
+보시다시피 샘플링된 토큰에 의해 텍스트 입력 토큰을 매번 증가시킵니다.
+
+매우 예외적인 경우를 제외하고, 대규모 언어 모델은 [인과적인 언어 모델링 목표](https://huggingface.co/docs/transformers/tasks/language_modeling#causal-language-modeling)를 사용하여 학습되므로 어텐션 점수의 상삼각 행렬을 마스킹합니다. 이것이 위의 두 다이어그램에서 어텐션 점수가 비어 있는 이유입니다 (즉, 0 확률을 가짐). 인과 언어 모델링에 대한 빠른 요약은 [*Illustrated Self Attention 블로그*](https://jalammar.github.io/illustrated-gpt2/#part-2-illustrated-self-attention)를 참조할 수 있습니다.
+
+결과적으로, 토큰은 *절대* 이전 토큰에 의존하지 않습니다. 더 구체적으로는 \\( \mathbf{q}_i \\) 벡터가 \\( j > i \\)인 경우 어떤 키, 값 벡터 \\( \mathbf{k}_j, \mathbf{v}j \\)와도 연관되지 않습니다. 대신 \\( \mathbf{q}i \\)는 이전의 키-값 벡터 \\( \mathbf{k}{m < i}, \mathbf{v}{m < i} \text{ , for } m \in {0, \ldots i - 1} \\)에만 주의를 기울입니다. 불필요한 계산을 줄이기 위해 각 층의 키-값 벡터를 모든 이전 시간 단계에 대해 캐시할 수 있습니다.
+
+다음으로, 대규모 언어 모델이 각 포워드 패스마다 키-값 캐시를 검색하고 전달하여 이를 활용하도록 합니다.
+Transformers에서는 `forward` 호출에 `use_cache` 플래그를 전달하여 키-값 캐시를 검색한 다음 현재 토큰과 함께 전달할 수 있습니다.
+
+```python
+past_key_values = None # past_key_values 는 키-값 캐시를 의미
+generated_tokens = []
+next_token_id = tokenizer(prompt, return_tensors="pt")["input_ids"].to("cuda")
+
+for _ in range(5):
+ next_logits, past_key_values = model(next_token_id, past_key_values=past_key_values, use_cache=True).to_tuple()
+ next_logits = next_logits[:, -1:]
+ next_token_id = torch.argmax(next_logits, dim=-1)
+
+ print("shape of input_ids", next_token_id.shape)
+ print("length of key-value cache", len(past_key_values[0][0])) # past_key_values 형태: [num_layers, 0 for k, 1 for v, batch_size, length, hidden_dim]
+ generated_tokens.append(next_token_id.item())
+
+generated_text = tokenizer.batch_decode(generated_tokens)
+generated_text
+```
+
+**출력**:
+```
+shape of input_ids torch.Size([1, 1])
+length of key-value cache 20
+shape of input_ids torch.Size([1, 1])
+length of key-value cache 21
+shape of input_ids torch.Size([1, 1])
+length of key-value cache 22
+shape of input_ids torch.Size([1, 1])
+length of key-value cache 23
+shape of input_ids torch.Size([1, 1])
+length of key-value cache 24
+[' Here', ' is', ' a', ' Python', ' function']
+```
+
+키-값 캐시를 사용할 때, 텍스트 입력 토큰의 길이는 *증가하지 않고* 단일 입력 벡터로 유지되는 것을 볼 수 있습니다. 반면에 키-값 캐시의 길이는 각 디코딩 단계마다 하나씩 증가합니다.
+
+> 키-값 캐시를 사용하면 \\( \mathbf{QK}^T \\)가 본질적으로 \\( \mathbf{q}_c\mathbf{K}^T \\)로 줄어드는데, 여기서 \\( \mathbf{q}_c \\)는 현재 전달된 입력 토큰의 쿼리 프로젝션으로, *항상* 단일 벡터입니다.
+
+키-값 캐시를 사용하는 것에는 두 가지 장점이 있습니다:
+- 전체 \\( \mathbf{QK}^T \\) 행렬을 계산하는 것과 비교하여 계산 효율성이 크게 향상됩니다. 이는 추론 속도의 증가로 이어집니다.
+- 생성된 토큰 수에 따라 필요한 최대 메모리가 이차적으로 증가하지 않고, 선형적으로만 증가합니다.
+
+> 더 긴 입력 시퀀스에 대해 동일한 결과와 큰 속도 향상을 가져오기 때문에 키-값 캐시를 *항상* 사용해야 합니다. Transformers는 텍스트 파이프라인이나 [`generate` 메서드](https://huggingface.co/docs/transformers/main_classes/text_generation)를 사용할 때 기본적으로 키-값 캐시를 활성화합니다.
+
+
+
+참고로, 키-값 캐시를 사용할 것을 권장하지만, 이를 사용할 때 LLM 출력이 약간 다를 수 있습니다. 이것은 행렬 곱셈 커널 자체의 특성 때문입니다 -- 더 자세한 내용은 [여기](https://github.com/huggingface/transformers/issues/25420#issuecomment-1775317535)에서 읽어볼 수 있습니다.
+
+
+
+#### 3.2.1 멀티 라운드 대화 [[321-multi-round-conversation]]
+
+키-값 캐시는 여러 번의 자기회귀 디코딩이 필요한 채팅과 같은 애플리케이션에 특히 유용합니다. 예제를 살펴보겠습니다.
+
+```
+User: How many people live in France?
+Assistant: Roughly 75 million people live in France
+User: And how many are in Germany?
+Assistant: Germany has ca. 81 million inhabitants
+```
+
+이 채팅에서 대규모 언어 모델은 두 번의 자기회귀 디코딩을 실행합니다:
+ 1. 첫 번째로, 키-값 캐시는 비어 있고 입력 프롬프트는 `"User: How many people live in France?"`입니다. 모델은 자기회귀적으로 `"Roughly 75 million people live in France"`라는 텍스트를 생성하며 디코딩 단계마다 키-값 캐시를 증가시킵니다.
+ 2. 두 번째로, 입력 프롬프트는 `"User: How many people live in France? \n Assistant: Roughly 75 million people live in France \n User: And how many in Germany?"`입니다. 캐시 덕분에 첫 번째 두 문장에 대한 모든 키-값 벡터는 이미 계산되어 있습니다. 따라서 입력 프롬프트는 `"User: And how many in Germany?"`로만 구성됩니다. 줄어든 입력 프롬프트를 처리하는 동안 계산된 키-값 벡터가 첫 번째 디코딩의 키-값 캐시에 연결됩니다. 두 번째 어시스턴트의 답변인 `"Germany has ca. 81 million inhabitants"`는 `"User: How many people live in France? \n Assistant: Roughly 75 million people live in France \n User: And how many are in Germany?"`의 인코딩된 키-값 벡터로 구성된 키-값 캐시를 사용하여 자기회귀적으로 생성됩니다.
+
+여기서 두 가지를 주목해야 합니다:
+ 1. 대규모 언어 모델이 대화의 모든 이전 문맥을 이해할 수 있도록 모든 문맥을 유지하는 것이 채팅에 배포된 대규모 언어 모델에서는 매우 중요합니다. 예를 들어, 위의 예에서 대규모 언어 모델은 사용자가 `"And how many are in Germany"`라고 물을 때 인구를 언급하고 있음을 이해해야 합니다.
+ 2. 키-값 캐시는 채팅에서 매우 유용합니다. 이는 인코딩된 채팅 기록을 처음부터 다시 인코딩할 필요 없이 계속해서 확장할 수 있게 해주기 때문입니다(예: 인코더-디코더 아키텍처를 사용할 때와 같은 경우).
+
+`transformers`에서 `generate` 호출은 기본적으로 `use_cache=True`와 함께 `return_dict_in_generate=True`를 전달하면 `past_key_values`를 반환합니다. 이는 아직 `pipeline` 인터페이스를 통해서는 사용할 수 없습니다.
+
+```python
+# 일반적인 생성
+prompt = system_prompt + "Question: Please write a function in Python that transforms bytes to Giga bytes.\n\nAnswer: Here"
+model_inputs = tokenizer(prompt, return_tensors='pt')
+generation_output = model.generate(**model_inputs, max_new_tokens=60, return_dict_in_generate=True)
+decoded_output = tokenizer.batch_decode(generation_output.sequences)[0]
+
+# 리턴된 `past_key_values`를 파이프라인화하여 다음 대화 라운드를 가속화
+prompt = decoded_output + "\nQuestion: How can I modify the function above to return Mega bytes instead?\n\nAnswer: Here"
+model_inputs = tokenizer(prompt, return_tensors='pt')
+generation_output = model.generate(
+ **model_inputs,
+ past_key_values=generation_output.past_key_values,
+ max_new_tokens=60,
+ return_dict_in_generate=True
+)
+tokenizer.batch_decode(generation_output.sequences)[0][len(prompt):]
+```
+
+**출력**:
+```
+ is a modified version of the function that returns Mega bytes instead.
+
+def bytes_to_megabytes(bytes):
+ return bytes / 1024 / 1024
+
+Answer: The function takes a number of bytes as input and returns the number of
+```
+
+훌륭합니다. 어텐션 층의 동일한 키와 값을 다시 계산하는 데 추가 시간이 소요되지 않습니다! 그러나 한 가지 문제가 있습니다. \\( \mathbf{QK}^T \\) 행렬에 필요한 최대 메모리는 크게 줄어들지만, 긴 입력 시퀀스나 다회차 채팅의 경우 키-값 캐시를 메모리에 보관하는 것이 매우 메모리 집약적이 될 수 있습니다. 키-값 캐시는 모든 자기 어텐션 층과 모든 어텐션 헤드에 대해 이전 입력 벡터 \\( \mathbf{x}_i \text{, for } i \in {1, \ldots, c - 1} \\)의 키-값 벡터를 저장해야 한다는 점을 기억하세요.
+
+이전에 사용한 대규모 언어 모델 `bigcode/octocoder`에 대해 키-값 캐시에 저장해야 하는 부동 소수점 값의 수를 계산해 봅시다.
+부동 소수점 값의 수는 시퀀스 길이의 두 배의 어텐션 헤드 수, 어텐션 헤드 차원, 레이어 수를 곱한 값입니다.
+가상의 입력 시퀀스 길이 16000에서 대규모 언어 모델에 대해 이를 계산하면 다음과 같습니다.
+
+```python
+config = model.config
+2 * 16_000 * config.n_layer * config.n_head * config.n_embd // config.n_head
+```
+
+**출력**:
+```
+7864320000
+```
+
+대략 80억 개의 부동 소수점 값입니다! `float16` 정밀도로 80억 개의 부동 소수점 값을 저장하는 데는 약 15GB의 RAM이 필요하며, 이는 모델 가중치 자체의 절반 정도입니다.
+연구자들은 키-값 캐시를 저장하는 데 필요한 메모리 비용을 크게 줄일 수 있는 두 가지 방법을 제안했으며, 이는 다음 절에서 살펴보겠습니다.
+
+#### 3.2.2 멀티 쿼리 어텐션 (MQA) [[322-multi-query-attention-mqa]]
+
+[멀티 쿼리 어텐션 (MQA)](https://arxiv.org/abs/1911.02150)은 Noam Shazeer의 *Fast Transformer Decoding: One Write-Head is All You Need* 논문에서 제안되었습니다. 제목에서 알 수 있듯이, Noam은 `n_head` 키-값 프로젝션 가중치 대신, 모든 어텐션 헤드에서 공유되는 단일 헤드-값 프로젝션 가중치를 사용할 수 있으며, 이를 통해 모델 성능이 크게 저하되지 않는다는 것을 발견했습니다.
+
+> 단일 헤드-값 프로젝션 가중치를 사용함으로써, 키-값 벡터 \\( \mathbf{k}_i, \mathbf{v}_i \\)는 모든 어텐션 헤드에서 동일해야 하며, 이는 캐시에 `n_head` 개 대신 하나의 키-값 프로젝션 쌍만 저장하면 된다는 것을 의미합니다.
+
+대부분의 대규모 언어 모델이 20에서 100 사이의 어텐션 헤드를 사용하기 때문에, MQA는 키-값 캐시의 메모리 소비를 크게 줄입니다. 이 노트북에서 사용된 대규모 언어 모델의 경우, 입력 시퀀스 길이 16000에서 필요한 메모리 소비를 15GB에서 400MB 미만으로 줄일 수 있습니다.
+
+메모리 절감 외에도, MQA는 계산 효율성도 향상시킵니다. 다음과 같이 설명합니다.
+자기회귀 디코딩에서는 큰 키-값 벡터를 다시 로드하고, 현재 키-값 벡터 쌍과 연결한 후 \\( \mathbf{q}_c\mathbf{K}^T \\) 계산에 매 단계마다 입력해야 합니다. 자기회귀 디코딩의 경우, 지속적인 재로드에 필요한 메모리 대역폭이 심각한 시간 병목 현상을 가져올 수 있습니다. 키-값 벡터의 크기를 줄이면 접근해야 하는 메모리 양이 줄어들어 메모리 대역폭 병목 현상이 감소합니다. 자세한 내용은 [Noam의 논문](https://arxiv.org/abs/1911.02150)을 참조하세요.
+
+여기서 이해해야 할 중요한 부분은 키-값 어텐션 헤드 수를 1로 줄이는 것이 키-값 캐시를 사용할 때만 의미가 있다는 것입니다. 키-값 캐시 없이 단일 포워드 패스에 대한 모델의 최대 메모리 소비는 변경되지 않으며, 각 어텐션 헤드는 여전히 고유한 쿼리 벡터를 가지므로 각 어텐션 헤드는 여전히 다른 \\( \mathbf{QK}^T \\) 행렬을 가집니다.
+
+MQA는 커뮤니티에서 널리 채택되어 현재 가장 인기 있는 많은 대규모 언어 모델에서 사용되고 있습니다.
+
+- [**Falcon**](https://huggingface.co/tiiuae/falcon-40b)
+- [**PaLM**](https://arxiv.org/abs/2204.02311)
+- [**MPT**](https://huggingface.co/mosaicml/mpt-30b)
+- [**BLOOM**](https://huggingface.co/bigscience/bloom)
+
+또한, 이 노트북에서 사용된 체크포인트 `bigcode/octocoder`는 MQA를 사용합니다.
+
+#### 3.2.3 그룹 쿼리 어텐션 (GQA) [[323-grouped-query-attention-gqa]]
+
+[그룹 쿼리 어텐션 (GQA)](https://arxiv.org/abs/2305.13245)은 Google의 Ainslie 등의 연구진들에 의해 제안되었습니다. 그들은 MQA를 사용하는 것이 종종 일반적인 멀티 키-값 헤드 프로젝션을 사용하는 것보다 품질 저하를 가져올 수 있다는 것을 발견했습니다. 이 논문은 쿼리 헤드 프로젝션 가중치의 수를 너무 극단적으로 줄이는 대신, 더 많은 모델 성능을 유지할 수 있다고 주장합니다. 단일 키-값 프로젝션 가중치 대신, `n < n_head` 키-값 프로젝션 가중치를 사용해야 합니다. `n_head`보다 훨씬 작은 `n`값, 예를 들어 2, 4 또는 8을 선택하면, MQA의 거의 모든 메모리 및 속도 이점을 유지하면서 모델 용량을 덜 희생하고 따라서 성능 저하를 줄일 수 있습니다.
+
+또한, GQA의 저자들은 기존 모델 체크포인트를 원래 사전 학습 계산의 5% 정도의 적은 양으로 GQA 아키텍처로 *업트레이닝*할 수 있음을 발견했습니다. 원래 사전 학습 계산의 5%가 여전히 엄청난 양일 수 있지만, GQA *업트레이닝*은 기존 체크포인트가 더 긴 입력 시퀀스에서도 유용하도록 합니다.
+
+GQA는 최근에 제안되었기 때문에 이 노트북을 작성할 당시에는 채택이 덜 되었습니다.
+GQA의 가장 주목할 만한 적용 사례는 [Llama-v2](https://huggingface.co/meta-llama/Llama-2-70b-hf)입니다.
+
+> 결론적으로, 대규모 언어 모델이 자기회귀 디코딩으로 배포되면서 채팅과 같이 큰 입력 시퀀스를 가진 작업을 처리해야 하는 경우 GQA 또는 MQA를 사용하는 것이 강력히 권장됩니다.
+
+
+## 결론 [[conclusion]]
+
+연구 커뮤니티는 점점 더 큰 대규모 언어 모델의 추론 시간을 가속화하기 위한 새로운 기발한 방법들을 끊임없이 찾아내고 있습니다. 예를 들어, [추측 디코딩](https://arxiv.org/abs/2211.17192)이라는 유망한 연구 방향이 있습니다. 여기서 "쉬운 토큰"은 더 작고 빠른 언어 모델에 의해 생성되고, "어려운 토큰"만 대규모 언어 모델 자체에 의해 생성됩니다. 자세한 내용은 이 노트북의 범위를 벗어나지만, [멋진 블로그 포스트](https://huggingface.co/blog/assisted-generation)에서 읽어볼 수 있습니다.
+
+GPT3/4, Llama-2-70b, Claude, PaLM과 같은 거대한 대규모 언어 모델이 [Hugging Face Chat](https://huggingface.co/chat/) 또는 ChatGPT와 같은 채팅 인터페이스에서 빠르게 실행될 수 있는 이유는 위에서 언급한 정밀도, 알고리즘, 아키텍처의 개선 덕분입니다. 앞으로 GPU, TPU 등과 같은 가속기는 점점 더 빨라지고 더 많은 메모리를 사용할 것입니다. 따라서 가장 좋은 알고리즘과 아키텍처를 사용하여 최고의 효율을 얻는 것이 중요합니다 🤗
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/agent.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/agent.md
new file mode 100644
index 0000000000000000000000000000000000000000..d0ef630e2cdf77f4d5755acdc06666c1bd78e88d
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/agent.md
@@ -0,0 +1,134 @@
+
+
+# 에이전트 & 도구 [[agents-tools]]
+
+
+
+Transformers Agent는 실험 중인 API이므로 언제든지 변경될 수 있습니다.
+API나 기반 모델이 자주 업데이트되므로, 에이전트가 제공하는 결과물은 달라질 수 있습니다.
+
+
+
+에이전트와 도구에 대해 더 알아보려면 [소개 가이드](../transformers_agents)를 꼭 읽어보세요.
+이 페이지에는 기본 클래스에 대한 API 문서가 포함되어 있습니다.
+
+## 에이전트 [[agents]]
+
+우리는 기본 [`Agent`] 클래스를 기반으로 두 가지 유형의 에이전트를 제공합니다:
+- [`CodeAgent`]는 한 번에 동작합니다. 작업을 해결하기 위해 코드를 생성한 다음, 바로 실행합니다.
+- [`ReactAgent`]는 단계별로 동작하며, 각 단계는 하나의 생각, 하나의 도구 호출 및 실행으로 구성됩니다. 이 에이전트에는 두 가지 클래스가 있습니다:
+ - [`ReactJsonAgent`]는 도구 호출을 JSON으로 작성합니다.
+ - [`ReactCodeAgent`]는 도구 호출을 Python 코드로 작성합니다.
+
+### Agent [[agent]]
+
+[[autodoc]] Agent
+
+### CodeAgent [[codeagent]]
+
+[[autodoc]] CodeAgent
+
+### React agents [[react-agents]]
+
+[[autodoc]] ReactAgent
+
+[[autodoc]] ReactJsonAgent
+
+[[autodoc]] ReactCodeAgent
+
+## Tools [[tools]]
+
+### load_tool [[loadtool]]
+
+[[autodoc]] load_tool
+
+### Tool [[tool]]
+
+[[autodoc]] Tool
+
+### Toolbox [[toolbox]]
+
+[[autodoc]] Toolbox
+
+### PipelineTool [[pipelinetool]]
+
+[[autodoc]] PipelineTool
+
+### launch_gradio_demo [[launchgradiodemo]]
+
+[[autodoc]] launch_gradio_demo
+
+### ToolCollection [[toolcollection]]
+
+[[autodoc]] ToolCollection
+
+## 엔진 [[engines]]
+
+에이전트 프레임워크에서 사용할 수 있는 엔진을 자유롭게 만들고 사용할 수 있습니다.
+이 엔진들은 다음과 같은 사양을 가지고 있습니다:
+1. 입력(`List[Dict[str, str]]`)에 대한 [메시지 형식](../chat_templating.md)을 따르고 문자열을 반환해야 합니다.
+2. 인수 `stop_sequences`에 시퀀스가 전달되기 *전에* 출력을 생성하는 것을 중지해야 합니다.
+
+### HfApiEngine [[HfApiEngine]]
+
+편의를 위해, 위의 사항을 구현하고 대규모 언어 모델 실행을 위해 추론 엔드포인트를 사용하는 `HfApiEngine`을 추가했습니다.
+
+```python
+>>> from transformers import HfApiEngine
+
+>>> messages = [
+... {"role": "user", "content": "Hello, how are you?"},
+... {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+... {"role": "user", "content": "No need to help, take it easy."},
+... ]
+
+>>> HfApiEngine()(messages, stop_sequences=["conversation"])
+
+"That's very kind of you to say! It's always nice to have a relaxed "
+```
+
+[[autodoc]] HfApiEngine
+
+
+## 에이전트 유형 [[agent-types]]
+
+에이전트는 도구 간의 모든 유형의 객체를 처리할 수 있습니다; 도구는 완전히 멀티모달이므로 텍스트, 이미지, 오디오, 비디오 등 다양한 유형을 수락하고 반환할 수 있습니다.
+도구 간의 호환성을 높이고 ipython (jupyter, colab, ipython 노트북, ...)에서 이러한
+반환 값을 올바르게 렌더링하기 위해 이러한 유형을 중심으로 래퍼 클래스를
+구현합니다.
+
+래핑된 객체는 처음과 동일하게 작동해야 합니다; 텍스트 객체는 여전히 문자열로 작동해야 하며,
+이미지 객체는 여전히 `PIL.Image`로 작동해야 합니다.
+
+이러한 유형에는 세 가지 특정 목적이 있습니다:
+
+- `to_raw`를 호출하면 기본 객체가 반환되어야 합니다.
+- `to_string`을 호출하면 객체가 문자열로 반환되어야 합니다:
+`AgentText`의 경우 문자열이 될 수 있지만, 다른 경우에는 객체의 직렬화된 버전의 경로일 수 있습니다.
+- ipython 커널에서 표시할 때 객체가 올바르게 표시되어야 합니다.
+
+### AgentText [[agenttext]]
+
+[[autodoc]] transformers.agents.agent_types.AgentText
+
+### AgentImage [[agentimage]]
+
+[[autodoc]] transformers.agents.agent_types.AgentImage
+
+### AgentAudio [[agentaudio]]
+
+[[autodoc]] transformers.agents.agent_types.AgentAudio
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/callback.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/callback.md
new file mode 100644
index 0000000000000000000000000000000000000000..1f280a412989e756b3882f10c9383233e60c08d0
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/callback.md
@@ -0,0 +1,133 @@
+
+
+# 콜백 [[callbacks]]
+
+콜백은 PyTorch [`Trainer`]의 반복 학습 동작을 사용자 정의할 수 있는 객체입니다
+(이 기능은 TensorFlow에서는 아직 구현되지 않았습니다). 콜백은 반복 학습의 상태를
+검사하여 (진행 상황 보고, TensorBoard 또는 기타 머신 러닝 플랫폼에 로그 남기기 등)
+결정(예: 조기 종료)을 내릴 수 있습니다.
+
+콜백은 [`TrainerControl`] 객체를 반환하는 것 외에는 반복 학습에서 어떤 것도 변경할 수 없는
+"읽기 전용" 코드 조각입니다. 반복 학습에 변경이 필요한 사용자 정의 작업이 필요한 경우,
+[`Trainer`]를 서브클래스로 만들어 필요한 메소드들을 오버라이드해야 합니다 (예시는 [trainer](trainer)를 참조하세요).
+
+기본적으로 `TrainingArguments.report_to`는 `"all"`로 설정되어 있으므로, [`Trainer`]는 다음 콜백을 사용합니다.
+
+- [`DefaultFlowCallback`]는 로그, 저장, 평가에 대한 기본 동작을 처리합니다.
+- [`PrinterCallback`] 또는 [`ProgressCallback`]는 진행 상황을 표시하고 로그를 출력합니다
+ ([`TrainingArguments`]를 통해 tqdm을 비활성화하면 첫 번째 콜백이 사용되고, 그렇지 않으면 두 번째가 사용됩니다).
+- [`~integrations.TensorBoardCallback`]는 TensorBoard가 (PyTorch >= 1.4
+ 또는 tensorboardX를 통해) 접근 가능하면 사용됩니다.
+- [`~integrations.WandbCallback`]는 [wandb](https://www.wandb.com/)가 설치되어 있으면
+ 사용됩니다.
+- [`~integrations.CometCallback`]는 [comet_ml](https://www.comet.com/site/)이 설치되어 있으면 사용됩니다.
+- [`~integrations.MLflowCallback`]는 [mlflow](https://www.mlflow.org/)가 설치되어 있으면 사용됩니다.
+- [`~integrations.NeptuneCallback`]는 [neptune](https://neptune.ai/)이 설치되어 있으면 사용됩니다.
+- [`~integrations.AzureMLCallback`]는 [azureml-sdk](https://pypi.org/project/azureml-sdk/)가 설치되어
+ 있으면 사용됩니다.
+- [`~integrations.CodeCarbonCallback`]는 [codecarbon](https://pypi.org/project/codecarbon/)이 설치되어
+ 있으면 사용됩니다.
+- [`~integrations.ClearMLCallback`]는 [clearml](https://github.com/allegroai/clearml)이 설치되어 있으면 사용됩니다.
+- [`~integrations.DagsHubCallback`]는 [dagshub](https://dagshub.com/)이 설치되어 있으면 사용됩니다.
+- [`~integrations.FlyteCallback`]는 [flyte](https://flyte.org/)가 설치되어 있으면 사용됩니다.
+- [`~integrations.DVCLiveCallback`]는 [dvclive](https://dvc.org/doc/dvclive)가 설치되어 있으면 사용됩니다.
+
+패키지가 설치되어 있지만 해당 통합 기능을 사용하고 싶지 않다면, `TrainingArguments.report_to`를 사용하고자 하는 통합 기능 목록으로 변경할 수 있습니다 (예: `["azure_ml", "wandb"]`).
+
+콜백을 구현하는 주요 클래스는 [`TrainerCallback`]입니다. 이 클래스는 [`Trainer`]를
+인스턴스화하는 데 사용된 [`TrainingArguments`]를 가져오고, 해당 Trainer의 내부 상태를
+[`TrainerState`]를 통해 접근할 수 있으며, [`TrainerControl`]을 통해 반복 학습에서 일부
+작업을 수행할 수 있습니다.
+
+
+## 사용 가능한 콜백 [[available-callbacks]]
+
+라이브러리에서 사용 가능한 [`TrainerCallback`] 목록은 다음과 같습니다:
+
+[[autodoc]] integrations.CometCallback
+ - setup
+
+[[autodoc]] DefaultFlowCallback
+
+[[autodoc]] PrinterCallback
+
+[[autodoc]] ProgressCallback
+
+[[autodoc]] EarlyStoppingCallback
+
+[[autodoc]] integrations.TensorBoardCallback
+
+[[autodoc]] integrations.WandbCallback
+ - setup
+
+[[autodoc]] integrations.MLflowCallback
+ - setup
+
+[[autodoc]] integrations.AzureMLCallback
+
+[[autodoc]] integrations.CodeCarbonCallback
+
+[[autodoc]] integrations.NeptuneCallback
+
+[[autodoc]] integrations.ClearMLCallback
+
+[[autodoc]] integrations.DagsHubCallback
+
+[[autodoc]] integrations.FlyteCallback
+
+[[autodoc]] integrations.DVCLiveCallback
+ - setup
+
+## TrainerCallback [[trainercallback]]
+
+[[autodoc]] TrainerCallback
+
+여기 PyTorch [`Trainer`]와 함께 사용자 정의 콜백을 등록하는 예시가 있습니다:
+
+```python
+class MyCallback(TrainerCallback):
+ "A callback that prints a message at the beginning of training"
+
+ def on_train_begin(self, args, state, control, **kwargs):
+ print("Starting training")
+
+
+trainer = Trainer(
+ model,
+ args,
+ train_dataset=train_dataset,
+ eval_dataset=eval_dataset,
+ callbacks=[MyCallback], # 우리는 콜백 클래스를 이 방식으로 전달하거나 그것의 인스턴스(MyCallback())를 전달할 수 있습니다
+)
+```
+
+또 다른 콜백을 등록하는 방법은 `trainer.add_callback()`을 호출하는 것입니다:
+
+```python
+trainer = Trainer(...)
+trainer.add_callback(MyCallback)
+# 다른 방법으로는 콜백 클래스의 인스턴스를 전달할 수 있습니다
+trainer.add_callback(MyCallback())
+```
+
+## TrainerState [[trainerstate]]
+
+[[autodoc]] TrainerState
+
+## TrainerControl [[trainercontrol]]
+
+[[autodoc]] TrainerControl
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/configuration.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/configuration.md
new file mode 100644
index 0000000000000000000000000000000000000000..6c6278a02585608a66a600cd610c81af995aaebf
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/configuration.md
@@ -0,0 +1,28 @@
+
+
+# 구성[[configuration]]
+
+기본 클래스 [`PretrainedConfig`]는 로컬 파일이나 디렉토리, 또는 라이브러리에서 제공하는 사전 학습된 모델 구성(HuggingFace의 AWS S3 저장소에서 다운로드됨)으로부터 구성을 불러오거나 저장하는 공통 메서드를 구현합니다. 각 파생 구성 클래스는 모델별 특성을 구현합니다.
+
+모든 구성 클래스에 존재하는 공통 속성은 다음과 같습니다: `hidden_size`, `num_attention_heads`, `num_hidden_layers`. 텍스트 모델은 추가로 `vocab_size`를 구현합니다.
+
+
+## PretrainedConfig[[transformers.PretrainedConfig]]
+
+[[autodoc]] PretrainedConfig
+ - push_to_hub
+ - all
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/data_collator.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/data_collator.md
new file mode 100644
index 0000000000000000000000000000000000000000..0e677c7d8979b87b418d800978174f1a65701f3a
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/data_collator.md
@@ -0,0 +1,66 @@
+
+
+# 데이터 콜레이터(Data Collator)[[data-collator]]
+
+데이터 콜레이터는 데이터셋 요소들의 리스트를 입력으로 사용하여 배치를 형성하는 객체입니다. 이러한 요소들은 `train_dataset` 또는 `eval_dataset의` 요소들과 동일한 타입 입니다. 배치를 구성하기 위해, 데이터 콜레이터는 (패딩과 같은) 일부 처리를 적용할 수 있습니다. [`DataCollatorForLanguageModeling`]과 같은 일부 콜레이터는 형성된 배치에 (무작위 마스킹과 같은) 일부 무작위 데이터 증강도 적용합니다. 사용 예시는 [예제 스크립트](../examples)나 [예제 노트북](../notebooks)에서 찾을 수 있습니다.
+
+
+## 기본 데이터 콜레이터[[transformers.default_data_collator]]
+
+[[autodoc]] data.data_collator.default_data_collator
+
+## DefaultDataCollator[[transformers.DefaultDataCollator]]
+
+[[autodoc]] data.data_collator.DefaultDataCollator
+
+## DataCollatorWithPadding[[transformers.DataCollatorWithPadding]]
+
+[[autodoc]] data.data_collator.DataCollatorWithPadding
+
+## DataCollatorForTokenClassification[[transformers.DataCollatorForTokenClassification]]
+
+[[autodoc]] data.data_collator.DataCollatorForTokenClassification
+
+## DataCollatorForSeq2Seq[[transformers.DataCollatorForSeq2Seq]]
+
+[[autodoc]] data.data_collator.DataCollatorForSeq2Seq
+
+## DataCollatorForLanguageModeling[[transformers.DataCollatorForLanguageModeling]]
+
+[[autodoc]] data.data_collator.DataCollatorForLanguageModeling
+ - numpy_mask_tokens
+ - tf_mask_tokens
+ - torch_mask_tokens
+
+## DataCollatorForWholeWordMask[[transformers.DataCollatorForWholeWordMask]]
+
+[[autodoc]] data.data_collator.DataCollatorForWholeWordMask
+ - numpy_mask_tokens
+ - tf_mask_tokens
+ - torch_mask_tokens
+
+## DataCollatorForPermutationLanguageModeling[[transformers.DataCollatorForPermutationLanguageModeling]]
+
+[[autodoc]] data.data_collator.DataCollatorForPermutationLanguageModeling
+ - numpy_mask_tokens
+ - tf_mask_tokens
+ - torch_mask_tokens
+
+## DataCollatorWithFlatteningtransformers.DataCollatorWithFlattening
+
+[[autodoc]] data.data_collator.DataCollatorWithFlattening
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/executorch.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/executorch.md
new file mode 100644
index 0000000000000000000000000000000000000000..a94418ece1a7abcc88b46afea148d02e89683c61
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/executorch.md
@@ -0,0 +1,33 @@
+
+
+
+# ExecuTorch [[executorch]]
+
+[`ExecuTorch`](https://github.com/pytorch/executorch) 는 웨어러블, 임베디드 장치, 마이크로컨트롤러를 포함한 모바일 및 엣지 장치에서 온디바이스 추론 기능을 가능하게 하는 종합 솔루션입니다. PyTorch 생태계에 속해있으며, 이식성, 생산성, 성능에 중점을 둔 PyTorch 모델 배포를 지원합니다.
+
+ExecuTorch는 백엔드 위임, 사용자 정의 컴파일러 변환, 메모리 계획 등 모델, 장치 또는 특정 유즈케이스 맞춤 최적화를 수행할 수 있는 진입점을 명확하게 정의합니다. ExecuTorch를 사용해 엣지 장치에서 PyTorch 모델을 실행하는 첫 번째 단계는 모델을 익스포트하는 것입니다. 이 작업은 PyTorch API인 [`torch.export`](https://pytorch.org/docs/stable/export.html)를 사용하여 수행합니다.
+
+
+## ExecuTorch 통합 [[transformers.TorchExportableModuleWithStaticCache]]
+
+`torch.export`를 사용하여 🤗 Transformers를 익스포트 할 수 있도록 통합 지점이 개발되고 있습니다. 이 통합의 목표는 익스포트뿐만 아니라, 익스포트한 아티팩트가 `ExecuTorch`에서 효율적으로 실행될 수 있도록 더 축소하고 최적화하는 것입니다. 특히 모바일 및 엣지 유즈케이스에 중점을 두고 있습니다.
+
+[[autodoc]] integrations.executorch.TorchExportableModuleWithStaticCache
+ - forward
+
+[[autodoc]] integrations.executorch.convert_and_export_with_cache
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/feature_extractor.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/feature_extractor.md
new file mode 100644
index 0000000000000000000000000000000000000000..7c667424c4ff956a1b1dce95db970b88d5aa7eb4
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/feature_extractor.md
@@ -0,0 +1,39 @@
+
+
+# 특성 추출기 [[feature-extractor]]
+
+특성 추출기는 오디오 또는 비전 모델을 위한 입력 특성을 준비하는 역할을 합니다. 여기에는 시퀀스에서 특성을 추출하는 작업(예를 들어, 오디오 파일을 전처리하여 Log-Mel 스펙트로그램 특성을 생성하는 것), 이미지에서 특성을 추출하는 작업(예를 들어, 이미지 파일을 자르는 것)이 포함됩니다. 뿐만 아니라 패딩, 정규화 및 NumPy, PyTorch, TensorFlow 텐서로의 변환도 포함됩니다.
+
+
+## FeatureExtractionMixin [[transformers.FeatureExtractionMixin]]
+
+[[autodoc]] feature_extraction_utils.FeatureExtractionMixin
+ - from_pretrained
+ - save_pretrained
+
+## SequenceFeatureExtractor [[transformers.SequenceFeatureExtractor]]
+
+[[autodoc]] SequenceFeatureExtractor
+ - pad
+
+## BatchFeature [[transformers.BatchFeature]]
+
+[[autodoc]] BatchFeature
+
+## ImageFeatureExtractionMixin [[transformers.ImageFeatureExtractionMixin]]
+
+[[autodoc]] image_utils.ImageFeatureExtractionMixin
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/keras_callbacks.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/keras_callbacks.md
new file mode 100644
index 0000000000000000000000000000000000000000..25d5ea3e40083acad8fa9257ce2c7cfef7c3d9c8
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/keras_callbacks.md
@@ -0,0 +1,27 @@
+
+
+# 케라스 콜백[[keras-callbacks]]
+
+케라스로 트랜스포머 모델을 학습할 때, 일반적인 작업을 자동화하기 위한 라이브러리 전용 콜백들을 사용 할 수 있습니다.
+
+## KerasMetricCallback[[transformers.KerasMetricCallback]]
+
+[[autodoc]] KerasMetricCallback
+
+## PushToHubCallback[[transformers.PushToHubCallback]]
+
+[[autodoc]] PushToHubCallback
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/logging.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/logging.md
new file mode 100644
index 0000000000000000000000000000000000000000..55e1a21c7bd57bb1b9f8e0f47052fa085340f65b
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/logging.md
@@ -0,0 +1,108 @@
+
+
+# 로깅 [[logging]]
+
+🤗 트랜스포머는 중앙 집중식 로깅 시스템을 제공하여 라이브러리의 출력 레벨을 쉽게 설정할 수 있습니다.
+
+현재 라이브러리의 기본 출력 레벨은 `WARNING`으로 설정되어 있습니다.
+
+출력 레벨을 변경하려면 직접적인 설정 메서드를 사용할 수 있습니다. 예를 들어, 출력 레벨을 INFO 수준으로 변경하는 방법은 다음과 같습니다.
+
+```python
+import transformers
+
+transformers.logging.set_verbosity_info()
+```
+
+환경 변수 `TRANSFORMERS_VERBOSITY`를 사용하여 기본 출력 레벨을 재정의할 수도 있습니다. 이를 `debug`, `info`, `warning`, `error`, `critical`, `fatal` 중 하나로 설정할 수 있습니다. 예를 들어 다음과 같습니다.
+
+```bash
+TRANSFORMERS_VERBOSITY=error ./myprogram.py
+```
+
+또한, 일부 `warnings`는 환경 변수 `TRANSFORMERS_NO_ADVISORY_WARNINGS`를 1과 같은 true 값으로 설정하여 비활성화할 수 있습니다. 이렇게 하면 [`logger.warning_advice`]를 사용하여 기록된 경고가 비활성화됩니다. 예를 들어 다음과 같습니다.
+
+```bash
+TRANSFORMERS_NO_ADVISORY_WARNINGS=1 ./myprogram.py
+```
+
+다음은 라이브러리와 동일한 로거를 자신의 모듈이나 스크립트에서 사용하는 방법에 대한 예시입니다.
+
+```python
+from transformers.utils import logging
+
+logging.set_verbosity_info()
+logger = logging.get_logger("transformers")
+logger.info("INFO")
+logger.warning("WARN")
+```
+
+
+이 로깅 모듈의 모든 메서드는 아래에 문서화되어 있으며, 주요 메서드는 현재 로거의 출력 수준을 가져오는 [`logging.get_verbosity`]와 원하는 출력 수준으로 설정하는 [`logging.set_verbosity`] 입니다. 출력 수준은 (가장 적은 출력에서 가장 많은 출력 순으로) 다음과 같으며, 해당 수준에 대응하는 정수 값은 괄호 안에 표시됩니다.
+
+- `transformers.logging.CRITICAL` 또는 `transformers.logging.FATAL` (정숫값, 50): 가장 심각한 오류만 보고합니다.
+- `transformers.logging.ERROR` (정숫값, 40): 오류만 보고합니다.
+- `transformers.logging.WARNING` 또는 `transformers.logging.WARN` (정숫값, 30): 오류와 경고만 보고합니다. 이는 라이브러리에서 기본으로 사용되는 수준입니다.
+- `transformers.logging.INFO` (정숫값, 20): 오류, 경고, 그리고 기본적인 정보를 보고합니다.
+- `transformers.logging.DEBUG` (정숫값, 10): 모든 정보를 보고합니다.
+
+기본적으로 모델 다운로드 중에는 `tqdm` 진행 표시줄이 표시됩니다. [`logging.disable_progress_bar`]와 [`logging.enable_progress_bar`]를 사용하여 이 동작을 숨기거나 다시 표시할 수 있습니다.
+
+## `logging` vs `warnings`[[transformers.utils.logging.captureWarnings]]
+
+Python에는 종종 함께 사용되는 두 가지 로깅 시스템이 있습니다. 위에서 설명한 `logging`과 `warnings`입니다. `warnings`는 특정 범주로 경고를 세분화할 수 있습니다. 예를 들어, 이미 더 이상 사용되지 않는 기능이나 경로에 대해 `FutureWarning`이 사용되고, 곧 사용 중단될 기능을 알리기 위해 `DeprecationWarning`이 사용됩니다.
+
+트랜스포머 라이브러리에서는 두 시스템 모두를 사용합니다. `logging`의 `captureWarnings` 메서드를 활용하고 이를 조정하여 위에서 설명한 출력 수준 설정자들을 통해 이러한 경고 메시지들을 관리할 수 있도록 합니다.
+
+라이브러리 개발자는 다음과 같은 지침을 따르는 것이 좋습니다.
+
+- `warnings`는 라이브러리 개발자와 `transformers`에 의존하는 라이브러리 개발자들에게 유리합니다.
+- `logging`은 일반적인 프로젝트 라이브러리 개발자보다는, 라이브러리를 사용하는 최종 사용자들에게 유리할 것입니다.
+
+아래에서 `captureWarnings` 메소드에 대한 참고 사항을 확인할 수 있습니다.
+
+[[autodoc]] logging.captureWarnings
+
+## 기본 설정자 [[transformers.utils.logging.set_verbosity_error]]
+
+[[autodoc]] logging.set_verbosity_error
+
+[[autodoc]] logging.set_verbosity_warning
+
+[[autodoc]] logging.set_verbosity_info
+
+[[autodoc]] logging.set_verbosity_debug
+
+## 기타 함수 [[transformers.utils.logging.get_verbosity]]
+
+[[autodoc]] logging.get_verbosity
+
+[[autodoc]] logging.set_verbosity
+
+[[autodoc]] logging.get_logger
+
+[[autodoc]] logging.enable_default_handler
+
+[[autodoc]] logging.disable_default_handler
+
+[[autodoc]] logging.enable_explicit_format
+
+[[autodoc]] logging.reset_format
+
+[[autodoc]] logging.enable_progress_bar
+
+[[autodoc]] logging.disable_progress_bar
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/model.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/model.md
new file mode 100644
index 0000000000000000000000000000000000000000..71a9768deee1ecf1badbbe60fe0152eb1756cde6
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/model.md
@@ -0,0 +1,68 @@
+
+
+# 모델
+
+기본 클래스 [`PreTrainedModel`], [`TFPreTrainedModel`], [`FlaxPreTrainedModel`]는 로컬 파일과 디렉토리로부터 모델을 로드하고 저장하거나 또는 (허깅페이스 AWS S3 리포지토리로부터 다운로드된) 라이브러리에서 제공하는 사전 훈련된 모델 설정을 로드하고 저장하는 것을 지원하는 기본 메소드를 구현하였습니다.
+
+[`PreTrainedModel`]과 [`TFPreTrainedModel`]은 또한 모든 모델들을 공통적으로 지원하는 메소드 여러개를 구현하였습니다:
+
+- 새 토큰이 단어장에 추가될 때, 입력 토큰 임베딩의 크기를 조정합니다.
+- 모델의 어텐션 헤드를 가지치기합니다.
+
+각 모델에 공통인 다른 메소드들은 다음의 클래스에서 정의됩니다.
+- [`~modeling_utils.ModuleUtilsMixin`](파이토치 모델용)
+- 텍스트 생성을 위한 [`~modeling_tf_utils.TFModuleUtilsMixin`](텐서플로 모델용)
+- [`~generation.GenerationMixin`](파이토치 모델용)
+- [`~generation.FlaxGenerationMixin`](Flax/JAX 모델용)
+
+## PreTrainedModel
+
+[[autodoc]] PreTrainedModel
+ - push_to_hub
+ - all
+
+사용자 정의 모델은 초고속 초기화(superfast init)가 특정 모델에 적용될 수 있는지 여부를 결정하는 `_supports_assign_param_buffer`도 포함해야 합니다.
+`test_save_and_load_from_pretrained` 실패 시, 모델이 `_supports_assign_param_buffer`를 필요로 하는지 확인하세요.
+필요로 한다면 `False`로 설정하세요.
+
+## ModuleUtilsMixin
+
+[[autodoc]] modeling_utils.ModuleUtilsMixin
+
+## TFPreTrainedModel
+
+[[autodoc]] TFPreTrainedModel
+ - push_to_hub
+ - all
+
+## TFModelUtilsMixin
+
+[[autodoc]] modeling_tf_utils.TFModelUtilsMixin
+
+## FlaxPreTrainedModel
+
+[[autodoc]] FlaxPreTrainedModel
+ - push_to_hub
+ - all
+
+## 허브에 저장하기
+
+[[autodoc]] utils.PushToHubMixin
+
+## 공유된 체크포인트
+
+[[autodoc]] modeling_utils.load_sharded_checkpoint
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/onnx.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/onnx.md
new file mode 100644
index 0000000000000000000000000000000000000000..510dab9df2f9332ca5a69252bd7c444e44bdf2e9
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/onnx.md
@@ -0,0 +1,50 @@
+
+
+# 🤗 Transformers 모델을 ONNX로 내보내기[[exporting--transformers-models-to-onnx]]
+
+🤗 트랜스포머는 `transformers.onnx` 패키지를 제공하며, 이 패키지는 설정 객체를 활용하여 모델 체크포인트를 ONNX 그래프로 변환할 수 있게 합니다.
+
+🤗 Transformers에 대한 자세한 내용은 [이 가이드](../serialization)를 참조하세요.
+
+## ONNX 설정[[onnx-configurations]]
+
+내보내려는(export) 모델 아키텍처의 유형에 따라 상속받아야 할 세 가지 추상 클래스를 제공합니다:
+
+* 인코더 기반 모델은 [`~onnx.config.OnnxConfig`]을 상속받습니다.
+* 디코더 기반 모델은 [`~onnx.config.OnnxConfigWithPast`]을 상속받습니다.
+* 인코더-디코더 기반 모델은 [`~onnx.config.OnnxSeq2SeqConfigWithPast`]을 상속받습니다.
+
+### OnnxConfig[[transformers.onnx.OnnxConfig]]
+
+[[autodoc]] onnx.config.OnnxConfig
+
+### OnnxConfigWithPast[[transformers.onnx.OnnxConfigWithPast]]
+
+[[autodoc]] onnx.config.OnnxConfigWithPast
+
+### OnnxSeq2SeqConfigWithPast[[OnnxSeq2SeqConfigWithPast]]
+
+[[autodoc]] onnx.config.OnnxSeq2SeqConfigWithPast
+
+## ONNX 특징[[onnx-features]]
+
+각 ONNX 설정은 다양한 유형의 토폴로지나 작업에 대해 모델을 내보낼 수 있게(exporting) 해주는 _features_ 세트와 연관되어 있습니다.
+
+### FeaturesManager[[transformers.onnx.FeaturesManager]]
+
+[[autodoc]] onnx.features.FeaturesManager
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/output.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/output.md
new file mode 100644
index 0000000000000000000000000000000000000000..e65a2c2c35906eef6cc4011994d4bdd50d9d3d76
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/output.md
@@ -0,0 +1,314 @@
+
+
+# 모델 출력[[model-outputs]]
+
+모든 모델에는 [`~utils.ModelOutput`]의 서브클래스의 인스턴스인 모델 출력이 있습니다. 이들은
+모델에서 반환되는 모든 정보를 포함하는 데이터 구조이지만 튜플이나 딕셔너리로도 사용할 수 있습니다.
+
+예제를 통해 살펴보겠습니다:
+
+```python
+from transformers import BertTokenizer, BertForSequenceClassification
+import torch
+
+tokenizer = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+model = BertForSequenceClassification.from_pretrained("google-bert/bert-base-uncased")
+
+inputs = tokenizer("Hello, my dog is cute", return_tensors="pt")
+labels = torch.tensor([1]).unsqueeze(0) # 배치 크기 1
+outputs = model(**inputs, labels=labels)
+```
+
+`outputs` 객체는 [`~modeling_outputs.SequenceClassifierOutput`]입니다.
+아래 해당 클래스의 문서에서 볼 수 있듯이, `loss`(선택적), `logits`, `hidden_states`(선택적) 및 `attentions`(선택적) 항목이 있습니다. 여기에서는 `labels`를 전달했기 때문에 `loss`가 있지만 `hidden_states`와 `attentions`가 없는데, 이는 `output_hidden_states=True` 또는 `output_attentions=True`를 전달하지 않았기 때문입니다.
+
+
+
+`output_hidden_states=True`를 전달할 때 `outputs.hidden_states[-1]`가 `outputs.last_hidden_state`와 정확히 일치할 것으로 예상할 수 있습니다.
+하지만 항상 그런 것은 아닙니다. 일부 모델은 마지막 은닉 상태가 반환될 때 정규화를 적용하거나 다른 후속 프로세스를 적용합니다.
+
+
+
+
+일반적으로 사용할 때와 동일하게 각 속성들에 접근할 수 있으며, 모델이 해당 속성을 반환하지 않은 경우 `None`이 반환됩니다. 예시에서는 `outputs.loss`는 모델에서 계산한 손실이고 `outputs.attentions`는 `None`입니다.
+
+`outputs` 객체를 튜플로 간주할 때는 `None` 값이 없는 속성만 고려합니다.
+예시에서는 `loss`와 `logits`라는 두 개의 요소가 있습니다. 그러므로,
+
+```python
+outputs[:2]
+```
+
+는 `(outputs.loss, outputs.logits)` 튜플을 반환합니다.
+
+`outputs` 객체를 딕셔너리로 간주할 때는 `None` 값이 없는 속성만 고려합니다.
+예시에는 `loss`와 `logits`라는 두 개의 키가 있습니다.
+
+여기서부터는 두 가지 이상의 모델 유형에서 사용되는 일반 모델 출력을 다룹니다. 구체적인 출력 유형은 해당 모델 페이지에 문서화되어 있습니다.
+
+## ModelOutput[[transformers.utils.ModelOutput]]
+
+[[autodoc]] utils.ModelOutput
+ - to_tuple
+
+## BaseModelOutput[[transformers.BaseModelOutput]]
+
+[[autodoc]] modeling_outputs.BaseModelOutput
+
+## BaseModelOutputWithPooling[[transformers.modeling_outputs.BaseModelOutputWithPooling]]
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPooling
+
+## BaseModelOutputWithCrossAttentions[[transformers.modeling_outputs.BaseModelOutputWithCrossAttentions]]
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithCrossAttentions
+
+## BaseModelOutputWithPoolingAndCrossAttentions[[transformers.modeling_outputs.BaseModelOutputWithPoolingAndCrossAttentions]]
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPoolingAndCrossAttentions
+
+## BaseModelOutputWithPast[[transformers.modeling_outputs.BaseModelOutputWithPast]]
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPast
+
+## BaseModelOutputWithPastAndCrossAttentions[[transformers.modeling_outputs.BaseModelOutputWithPastAndCrossAttentions]]
+
+[[autodoc]] modeling_outputs.BaseModelOutputWithPastAndCrossAttentions
+
+## Seq2SeqModelOutput[[transformers.modeling_outputs.Seq2SeqModelOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqModelOutput
+
+## CausalLMOutput[[transformers.modeling_outputs.CausalLMOutput]]
+
+[[autodoc]] modeling_outputs.CausalLMOutput
+
+## CausalLMOutputWithCrossAttentions[[transformers.modeling_outputs.CausalLMOutputWithCrossAttentions]]
+
+[[autodoc]] modeling_outputs.CausalLMOutputWithCrossAttentions
+
+## CausalLMOutputWithPast[[transformers.modeling_outputs.CausalLMOutputWithPast]]
+
+[[autodoc]] modeling_outputs.CausalLMOutputWithPast
+
+## MaskedLMOutput[[transformers.modeling_outputs.MaskedLMOutput]]
+
+[[autodoc]] modeling_outputs.MaskedLMOutput
+
+## Seq2SeqLMOutput[[transformers.modeling_outputs.Seq2SeqLMOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqLMOutput
+
+## NextSentencePredictorOutput[[transformers.modeling_outputs.NextSentencePredictorOutput]]
+
+[[autodoc]] modeling_outputs.NextSentencePredictorOutput
+
+## SequenceClassifierOutput[[transformers.modeling_outputs.SequenceClassifierOutput]]
+
+[[autodoc]] modeling_outputs.SequenceClassifierOutput
+
+## Seq2SeqSequenceClassifierOutput[[transformers.modeling_outputs.Seq2SeqSequenceClassifierOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqSequenceClassifierOutput
+
+## MultipleChoiceModelOutput[[transformers.modeling_outputs.MultipleChoiceModelOutput]]
+
+[[autodoc]] modeling_outputs.MultipleChoiceModelOutput
+
+## TokenClassifierOutput[[transformers.modeling_outputs.TokenClassifierOutput]]
+
+[[autodoc]] modeling_outputs.TokenClassifierOutput
+
+## QuestionAnsweringModelOutput[[transformers.modeling_outputs.QuestionAnsweringModelOutput]]
+
+[[autodoc]] modeling_outputs.QuestionAnsweringModelOutput
+
+## Seq2SeqQuestionAnsweringModelOutput[[transformers.modeling_outputs.Seq2SeqQuestionAnsweringModelOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqQuestionAnsweringModelOutput
+
+## Seq2SeqSpectrogramOutput[[transformers.modeling_outputs.Seq2SeqSpectrogramOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqSpectrogramOutput
+
+## SemanticSegmenterOutput[[transformers.modeling_outputs.SemanticSegmenterOutput]]
+
+[[autodoc]] modeling_outputs.SemanticSegmenterOutput
+
+## ImageClassifierOutput[[transformers.modeling_outputs.ImageClassifierOutput]]
+
+[[autodoc]] modeling_outputs.ImageClassifierOutput
+
+## ImageClassifierOutputWithNoAttention[[transformers.modeling_outputs.ImageClassifierOutputWithNoAttention]]
+
+[[autodoc]] modeling_outputs.ImageClassifierOutputWithNoAttention
+
+## DepthEstimatorOutput[[transformers.modeling_outputs.DepthEstimatorOutput]]
+
+[[autodoc]] modeling_outputs.DepthEstimatorOutput
+
+## Wav2Vec2BaseModelOutput[[transformers.modeling_outputs.Wav2Vec2BaseModelOutput]]
+
+[[autodoc]] modeling_outputs.Wav2Vec2BaseModelOutput
+
+## XVectorOutput[[transformers.modeling_outputs.XVectorOutput]]
+
+[[autodoc]] modeling_outputs.XVectorOutput
+
+## Seq2SeqTSModelOutput[[transformers.modeling_outputs.Seq2SeqTSModelOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqTSModelOutput
+
+## Seq2SeqTSPredictionOutput[[transformers.modeling_outputs.Seq2SeqTSPredictionOutput]]
+
+[[autodoc]] modeling_outputs.Seq2SeqTSPredictionOutput
+
+## SampleTSPredictionOutput[[transformers.modeling_outputs.SampleTSPredictionOutput]]
+
+[[autodoc]] modeling_outputs.SampleTSPredictionOutput
+
+## TFBaseModelOutput[[transformers.modeling_outputs.TFBaseModelOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutput
+
+## TFBaseModelOutputWithPooling[[transformers.modeling_tf_outputs.TFBaseModelOutputWithPooling]]
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPooling
+
+## TFBaseModelOutputWithPoolingAndCrossAttentions[[transformers.modeling_tf_outputs.TFBaseModelOutputWithPoolingAndCrossAttentions]]
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPoolingAndCrossAttentions
+
+## TFBaseModelOutputWithPast[[transformers.modeling_tf_outputs.TFBaseModelOutputWithPast]]
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPast
+
+## TFBaseModelOutputWithPastAndCrossAttentions[[transformers.modeling_tf_outputs.TFBaseModelOutputWithPastAndCrossAttentions]]
+
+[[autodoc]] modeling_tf_outputs.TFBaseModelOutputWithPastAndCrossAttentions
+
+## TFSeq2SeqModelOutput[[transformers.modeling_tf_outputs.TFSeq2SeqModelOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqModelOutput
+
+## TFCausalLMOutput[[transformers.modeling_tf_outputs.TFCausalLMOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFCausalLMOutput
+
+## TFCausalLMOutputWithCrossAttentions[[transformers.modeling_tf_outputs.TFCausalLMOutputWithCrossAttentions]]
+
+[[autodoc]] modeling_tf_outputs.TFCausalLMOutputWithCrossAttentions
+
+## TFCausalLMOutputWithPast[[transformers.modeling_tf_outputs.TFCausalLMOutputWithPast]]
+
+[[autodoc]] modeling_tf_outputs.TFCausalLMOutputWithPast
+
+## TFMaskedLMOutput[[transformers.modeling_tf_outputs.TFMaskedLMOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFMaskedLMOutput
+
+## TFSeq2SeqLMOutput[[transformers.modeling_tf_outputs.TFSeq2SeqLMOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqLMOutput
+
+## TFNextSentencePredictorOutput[[transformers.modeling_tf_outputs.TFNextSentencePredictorOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFNextSentencePredictorOutput
+
+## TFSequenceClassifierOutput[[transformers.modeling_tf_outputs.TFSequenceClassifierOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFSequenceClassifierOutput
+
+## TFSeq2SeqSequenceClassifierOutput[[transformers.modeling_tf_outputs.TFSeq2SeqSequenceClassifierOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqSequenceClassifierOutput
+
+## TFMultipleChoiceModelOutput[[transformers.modeling_tf_outputs.TFMultipleChoiceModelOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFMultipleChoiceModelOutput
+
+## TFTokenClassifierOutput[[transformers.modeling_tf_outputs.TFTokenClassifierOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFTokenClassifierOutput
+
+## TFQuestionAnsweringModelOutput[[transformers.modeling_tf_outputs.TFQuestionAnsweringModelOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFQuestionAnsweringModelOutput
+
+## TFSeq2SeqQuestionAnsweringModelOutput[[transformers.modeling_tf_outputs.TFSeq2SeqQuestionAnsweringModelOutput]]
+
+[[autodoc]] modeling_tf_outputs.TFSeq2SeqQuestionAnsweringModelOutput
+
+## FlaxBaseModelOutput[[transformers.modeling_flax_outputs.FlaxBaseModelOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutput
+
+## FlaxBaseModelOutputWithPast[[transformers.modeling_flax_outputs.FlaxBaseModelOutputWithPast]]
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutputWithPast
+
+## FlaxBaseModelOutputWithPooling[[transformers.modeling_flax_outputs.FlaxBaseModelOutputWithPooling]]
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutputWithPooling
+
+## FlaxBaseModelOutputWithPastAndCrossAttentions[[transformers.modeling_flax_outputs.FlaxBaseModelOutputWithPastAndCrossAttentions]]
+
+[[autodoc]] modeling_flax_outputs.FlaxBaseModelOutputWithPastAndCrossAttentions
+
+## FlaxSeq2SeqModelOutput[[transformers.modeling_flax_outputs.FlaxSeq2SeqModelOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqModelOutput
+
+## FlaxCausalLMOutputWithCrossAttentions[[transformers.modeling_flax_outputs.FlaxCausalLMOutputWithCrossAttentions]]
+
+[[autodoc]] modeling_flax_outputs.FlaxCausalLMOutputWithCrossAttentions
+
+## FlaxMaskedLMOutput[[transformers.modeling_flax_outputs.FlaxMaskedLMOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxMaskedLMOutput
+
+## FlaxSeq2SeqLMOutput[[transformers.modeling_flax_outputs.FlaxSeq2SeqLMOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqLMOutput
+
+## FlaxNextSentencePredictorOutput[[transformers.modeling_flax_outputs.FlaxNextSentencePredictorOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxNextSentencePredictorOutput
+
+## FlaxSequenceClassifierOutput[[transformers.modeling_flax_outputs.FlaxSequenceClassifierOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxSequenceClassifierOutput
+
+## FlaxSeq2SeqSequenceClassifierOutput[[transformers.modeling_flax_outputs.FlaxSeq2SeqSequenceClassifierOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqSequenceClassifierOutput
+
+## FlaxMultipleChoiceModelOutput[[transformers.modeling_flax_outputs.FlaxMultipleChoiceModelOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxMultipleChoiceModelOutput
+
+## FlaxTokenClassifierOutput[[transformers.modeling_flax_outputs.FlaxTokenClassifierOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxTokenClassifierOutput
+
+## FlaxQuestionAnsweringModelOutput[[transformers.modeling_flax_outputs.FlaxQuestionAnsweringModelOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxQuestionAnsweringModelOutput
+
+## FlaxSeq2SeqQuestionAnsweringModelOutput[[transformers.modeling_flax_outputs.FlaxSeq2SeqQuestionAnsweringModelOutput]]
+
+[[autodoc]] modeling_flax_outputs.FlaxSeq2SeqQuestionAnsweringModelOutput
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/quantization.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/quantization.md
new file mode 100644
index 0000000000000000000000000000000000000000..6f793f2210741788cf67a2e2a8232c654ea77484
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/quantization.md
@@ -0,0 +1,75 @@
+
+
+# 양자화[[quantization]]
+
+
+
+양자화 기법은 가중치와 활성화를 8비트 정수(int8)와 같은 더 낮은 정밀도의 데이터 타입으로 표현함으로써 메모리와 계산 비용을 줄입니다. 이를 통해 일반적으로는 메모리에 올릴 수 없는 더 큰 모델을 로드할 수 있고, 추론 속도를 높일 수 있습니다. Transformers는 AWQ와 GPTQ 양자화 알고리즘을 지원하며, bitsandbytes를 통해 8비트와 4비트 양자화를 지원합니다.
+Transformers에서 지원되지 않는 양자화 기법들은 [`HfQuantizer`] 클래스를 통해 추가될 수 있습니다.
+
+
+
+모델을 양자화하는 방법은 이 [양자화](../quantization) 가이드를 통해 배울 수 있습니다.
+
+
+
+## QuantoConfig[[transformers.QuantoConfig]]
+
+[[autodoc]] QuantoConfig
+
+## AqlmConfig[[transformers.AqlmConfig]]
+
+[[autodoc]] AqlmConfig
+
+## VptqConfig[[transformers.VptqConfig]]
+
+[[autodoc]] VptqConfig
+
+## AwqConfig[[transformers.AwqConfig]]
+
+[[autodoc]] AwqConfig
+
+## EetqConfig[[transformers.EetqConfig]]
+[[autodoc]] EetqConfig
+
+## GPTQConfig[[transformers.GPTQConfig]]
+
+[[autodoc]] GPTQConfig
+
+## BitsAndBytesConfig[[#transformers.BitsAndBytesConfig]]
+
+[[autodoc]] BitsAndBytesConfig
+
+## HfQuantizer[[transformers.quantizers.HfQuantizer]]
+
+[[autodoc]] quantizers.base.HfQuantizer
+
+## HqqConfig[[transformers.HqqConfig]]
+
+[[autodoc]] HqqConfig
+
+## FbgemmFp8Config[[transformers.FbgemmFp8Config]]
+
+[[autodoc]] FbgemmFp8Config
+
+## CompressedTensorsConfig[[transformers.CompressedTensorsConfig]]
+
+[[autodoc]] CompressedTensorsConfig
+
+## TorchAoConfig[[transformers.TorchAoConfig]]
+
+[[autodoc]] TorchAoConfig
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/text_generation.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/text_generation.md
new file mode 100644
index 0000000000000000000000000000000000000000..917d995e6ec15c4a642e2c3bf4c5fc7b865fdb85
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/text_generation.md
@@ -0,0 +1,56 @@
+
+
+# 생성 [[generation]]
+
+각 프레임워크에는 해당하는 `GenerationMixin` 클래스에서 구현된 텍스트 생성을 위한 generate 메소드가 있습니다:
+
+- PyTorch에서는 [`~generation.GenerationMixin.generate`]가 [`~generation.GenerationMixin`]에 구현되어 있습니다.
+- TensorFlow에서는 [`~generation.TFGenerationMixin.generate`]가 [`~generation.TFGenerationMixin`]에 구현되어 있습니다.
+- Flax/JAX에서는 [`~generation.FlaxGenerationMixin.generate`]가 [`~generation.FlaxGenerationMixin`]에 구현되어 있습니다.
+
+사용하는 프레임워크에 상관없이, generate 메소드는 [`~generation.GenerationConfig`] 클래스 인스턴스로 매개변수화 할 수 있습니다. generate 메소드의 동작을 제어하는 모든 생성 매개변수 목록을 확인하려면 이 클래스를 참조하세요.
+
+모델의 생성 설정을 어떻게 확인하고, 기본값이 무엇인지, 매개변수를 어떻게 임시로 변경하는지, 그리고 사용자 지정 생성 설정을 만들고 저장하는 방법을 배우려면 [텍스트 생성 전략 가이드](../generation_strategies)를 참조하세요. 이 가이드는 토큰 스트리밍과 같은 관련 기능을 사용하는 방법도 설명합니다.
+
+## GenerationConfig [[transformers.GenerationConfig]]
+
+[[autodoc]] generation.GenerationConfig
+ - from_pretrained
+ - from_model_config
+ - save_pretrained
+ - update
+ - validate
+ - get_generation_mode
+
+[[autodoc]] generation.WatermarkingConfig
+
+## GenerationMixin [[transformers.GenerationMixin]]
+
+[[autodoc]] generation.GenerationMixin
+ - generate
+ - compute_transition_scores
+
+## TFGenerationMixin [[transformers.TFGenerationMixin]]
+
+[[autodoc]] generation.TFGenerationMixin
+ - generate
+ - compute_transition_scores
+
+## FlaxGenerationMixin [[transformers.FlaxGenerationMixin]]
+
+[[autodoc]] generation.FlaxGenerationMixin
+ - generate
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/trainer.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/trainer.md
new file mode 100644
index 0000000000000000000000000000000000000000..23eda74a8bd669c16fcb3ebdbd21ea7cd8d6cd65
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/main_classes/trainer.md
@@ -0,0 +1,52 @@
+
+
+# Trainer [[trainer]]
+
+[`Trainer`] 클래스는 PyTorch에서 완전한 기능(feature-complete)의 훈련을 위한 API를 제공하며, 다중 GPU/TPU에서의 분산 훈련, [NVIDIA GPU](https://nvidia.github.io/apex/), [AMD GPU](https://rocm.docs.amd.com/en/latest/rocm.html)를 위한 혼합 정밀도, 그리고 PyTorch의 [`torch.amp`](https://pytorch.org/docs/stable/amp.html)를 지원합니다. [`Trainer`]는 모델의 훈련 방식을 커스터마이즈할 수 있는 다양한 옵션을 제공하는 [`TrainingArguments`] 클래스와 함께 사용됩니다. 이 두 클래스는 함께 완전한 훈련 API를 제공합니다.
+
+[`Seq2SeqTrainer`]와 [`Seq2SeqTrainingArguments`]는 [`Trainer`]와 [`TrainingArguments`] 클래스를 상속하며, 요약이나 번역과 같은 시퀀스-투-시퀀스 작업을 위한 모델 훈련에 적합하게 조정되어 있습니다.
+
+
+
+[`Trainer`] 클래스는 🤗 Transformers 모델에 최적화되어 있으며, 다른 모델과 함께 사용될 때 예상치 못한 동작을 하게 될 수 있습니다. 자신만의 모델을 사용할 때는 다음을 확인하세요:
+
+- 모델은 항상 튜플이나 [`~utils.ModelOutput`]의 서브클래스를 반환해야 합니다.
+- 모델은 `labels` 인자가 제공되면 손실을 계산할 수 있고, 모델이 튜플을 반환하는 경우 그 손실이 튜플의 첫 번째 요소로 반환되어야 합니다.
+- 모델은 여러 개의 레이블 인자를 수용할 수 있어야 하며, [`Trainer`]에게 이름을 알리기 위해 [`TrainingArguments`]에서 `label_names`를 사용하지만, 그 중 어느 것도 `"label"`로 명명되어서는 안 됩니다.
+
+
+
+## Trainer [[transformers.Trainer]]
+
+[[autodoc]] Trainer
+ - all
+
+## Seq2SeqTrainer [[transformers.Seq2SeqTrainer]]
+
+[[autodoc]] Seq2SeqTrainer
+ - evaluate
+ - predict
+
+## TrainingArguments [[transformers.TrainingArguments]]
+
+[[autodoc]] TrainingArguments
+ - all
+
+## Seq2SeqTrainingArguments [[transformers.Seq2SeqTrainingArguments]]
+
+[[autodoc]] Seq2SeqTrainingArguments
+ - all
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/altclip.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/altclip.md
new file mode 100644
index 0000000000000000000000000000000000000000..1236bcc9aaa7da8da5fb4820bb87b3f9413cb805
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/altclip.md
@@ -0,0 +1,78 @@
+# AltCLIP
+
+## 개요[[overview]]
+
+AltCLIP 모델은 Zhongzhi Chen, Guang Liu, Bo-Wen Zhang, Fulong Ye, Qinghong Yang, Ledell Wu의 [AltCLIP: Altering the Language Encoder in CLIP for Extended Language Capabilities](https://arxiv.org/abs/2211.06679v2) 논문에서 제안되었습니다. AltCLIP(CLIP의 언어 인코더를 변경하여 언어 기능 확장)은 다양한 이미지-텍스트 및 텍스트-텍스트 쌍으로 훈련된 신경망입니다. CLIP의 텍스트 인코더를 사전 훈련된 다국어 텍스트 인코더 XLM-R로 교체하여, 거의 모든 작업에서 CLIP과 유사한 성능을 얻을 수 있었으며, 원래 CLIP의 다국어 이해와 같은 기능도 확장되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*본 연구에서는 강력한 이중 언어 멀티모달 표현 모델을 훈련하는 개념적으로 간단하고 효과적인 방법을 제시합니다. OpenAI에서 출시한 사전 훈련된 멀티모달 표현 모델 CLIP에서 시작하여, 그 텍스트 인코더를 사전 훈련된 다국어 텍스트 인코더 XLM-R로 교체하고, 교사 학습과 대조 학습으로 구성된 2단계 훈련 스키마를 통해 언어와 이미지 표현을 정렬했습니다. 우리는 광범위한 작업 평가를 통해 우리의 방법을 검증했습니다. ImageNet-CN, Flicker30k-CN, COCO-CN을 포함한 여러 작업에서 새로운 최고 성능을 달성했으며, 거의 모든 작업에서 CLIP과 유사한 성능을 얻었습니다. 이는 CLIP의 텍스트 인코더를 단순히 변경하여 다국어 이해와 같은 확장 기능을 얻을 수 있음을 시사합니다.*
+
+이 모델은 [jongjyh](https://huggingface.co/jongjyh)에 의해 기여되었습니다.
+
+## 사용 팁과 예제[[usage-tips-and-example]]
+
+AltCLIP의 사용법은 CLIP과 매우 유사하며, 차이점은 텍스트 인코더에 있습니다. 일반적인 어텐션 대신 양방향 어텐션을 사용하며, XLM-R의 [CLS] 토큰을 사용하여 텍스트 임베딩을 나타냅니다.
+
+AltCLIP은 멀티모달 비전 및 언어 모델입니다. 이미지와 텍스트 간의 유사성 계산 및 제로샷 이미지 분류에 사용할 수 있습니다. AltCLIP은 ViT와 같은 트랜스포머를 사용하여 시각적 특징을 얻고, 양방향 언어 모델을 사용하여 텍스트 특징을 얻습니다. 이후 텍스트와 시각적 특징 모두 동일한 차원의 잠재 공간으로 투사됩니다. 투사된 이미지와 텍스트 특징 간의 내적을 유사도 점수로 사용합니다.
+
+이미지를 트랜스포머 인코더에 입력하기 위해, 각 이미지를 일정한 크기의 겹치지 않는 패치 시퀀스로 분할한 뒤, 이를 선형 임베딩합니다. 전체 이미지를 나타내기 위해 [CLS] 토큰이 추가됩니다. 저자들은 절대 위치 임베딩도 추가하여 결과 벡터 시퀀스를 표준 트랜스포머 인코더에 입력합니다. [`CLIPImageProcessor`]는 모델을 위해 이미지를 크기 조정하고 정규화하는 데 사용할 수 있습니다.
+
+[`AltCLIPProcessor`]는 [`CLIPImageProcessor`]와 [`XLMRobertaTokenizer`]를 하나의 인스턴스로 묶어 텍스트를 인코딩하고 이미지를 준비합니다. 다음 예제는 [`AltCLIPProcessor`]와 [`AltCLIPModel`]을 사용하여 이미지와 텍스트 간의 유사성 점수를 얻는 방법을 보여줍니다.
+```python
+>>> from PIL import Image
+>>> import requests
+
+>>> from transformers import AltCLIPModel, AltCLIPProcessor
+
+>>> model = AltCLIPModel.from_pretrained("BAAI/AltCLIP")
+>>> processor = AltCLIPProcessor.from_pretrained("BAAI/AltCLIP")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> inputs = processor(text=["a photo of a cat", "a photo of a dog"], images=image, return_tensors="pt", padding=True)
+
+>>> outputs = model(**inputs)
+>>> logits_per_image = outputs.logits_per_image # 이미지-텍스트 유사도 점수
+>>> probs = logits_per_image.softmax(dim=1) # 라벨 마다 확률을 얻기 위해 softmax 적용
+```
+
+
+이 모델은 `CLIPModel`을 기반으로 하므로, 원래 CLIP처럼 사용할 수 있습니다.
+
+
+
+## AltCLIPConfig
+
+[[autodoc]] AltCLIPConfig
+ - from_text_vision_configs
+
+## AltCLIPTextConfig
+
+[[autodoc]] AltCLIPTextConfig
+
+## AltCLIPVisionConfig
+
+[[autodoc]] AltCLIPVisionConfig
+
+## AltCLIPProcessor
+
+[[autodoc]] AltCLIPProcessor
+
+## AltCLIPModel
+
+[[autodoc]] AltCLIPModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## AltCLIPTextModel
+
+[[autodoc]] AltCLIPTextModel
+ - forward
+
+## AltCLIPVisionModel
+
+[[autodoc]] AltCLIPVisionModel
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/auto.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/auto.md
new file mode 100644
index 0000000000000000000000000000000000000000..cda00adc33a663c1b426a61f10ace8d708936da8
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/auto.md
@@ -0,0 +1,375 @@
+
+
+# Auto 클래스[[auto-classes]]
+
+많은 경우, 사용하려는 아키텍처는 `from_pretrained()` 메소드에서 제공하는 사전 훈련된 모델의 이름이나 경로로부터 유추할 수 있습니다. AutoClasses는 이 작업을 위해 존재하며, 사전 학습된 모델 가중치/구성/단어사전에 대한 이름/경로를 제공하면 자동으로 관련 모델을 가져오도록 도와줍니다.
+
+[`AutoConfig`], [`AutoModel`], [`AutoTokenizer`] 중 하나를 인스턴스화하면 해당 아키텍처의 클래스를 직접 생성합니다. 예를 들어,
+
+
+```python
+model = AutoModel.from_pretrained("google-bert/bert-base-cased")
+```
+
+위 코드는 [`BertModel`]의 인스턴스인 모델을 생성합니다.
+
+각 작업에 대해 하나의 `AutoModel` 클래스가 있으며, 각각의 백엔드(PyTorch, TensorFlow 또는 Flax)에 해당하는 클래스가 존재합니다.
+
+## 자동 클래스 확장[[extending-the-auto-classes]]
+
+각 자동 클래스는 사용자의 커스텀 클래스로 확장될 수 있는 메소드를 가지고 있습니다. 예를 들어, `NewModel`이라는 커스텀 모델 클래스를 정의했다면, `NewModelConfig`를 준비한 후 다음과 같이 자동 클래스에 추가할 수 있습니다:
+
+```python
+from transformers import AutoConfig, AutoModel
+
+AutoConfig.register("new-model", NewModelConfig)
+AutoModel.register(NewModelConfig, NewModel)
+```
+
+이후에는 일반적으로 자동 클래스를 사용하는 것처럼 사용할 수 있습니다!
+
+
+
+만약 `NewModelConfig`가 [`~transformers.PretrainedConfig`]의 서브클래스라면, 해당 `model_type` 속성이 등록할 때 사용하는 키(여기서는 `"new-model"`)와 동일하게 설정되어 있는지 확인하세요.
+
+마찬가지로, `NewModel`이 [`PreTrainedModel`]의 서브클래스라면, 해당 `config_class` 속성이 등록할 때 사용하는 클래스(여기서는 `NewModelConfig`)와 동일하게 설정되어 있는지 확인하세요.
+
+
+
+## AutoConfig[[transformers.AutoConfig]]
+
+[[autodoc]] AutoConfig
+
+## AutoTokenizer[[transformers.AutoTokenizer]]
+
+[[autodoc]] AutoTokenizer
+
+## AutoFeatureExtractor[[transformers.AutoFeatureExtractor]]
+
+[[autodoc]] AutoFeatureExtractor
+
+## AutoImageProcessor[[transformers.AutoImageProcessor]]
+
+[[autodoc]] AutoImageProcessor
+
+## AutoProcessor[[transformers.AutoProcessor]]
+
+[[autodoc]] AutoProcessor
+
+## 일반적인 모델 클래스[[generic-model-classes]]
+
+다음 자동 클래스들은 특정 헤드 없이 기본 모델 클래스를 인스턴스화하는 데 사용할 수 있습니다.
+
+### AutoModel[[transformers.AutoModel]]
+
+[[autodoc]] AutoModel
+
+### TFAutoModel[[transformers.TFAutoModel]]
+
+[[autodoc]] TFAutoModel
+
+### FlaxAutoModel[[transformers.FlaxAutoModel]]
+
+[[autodoc]] FlaxAutoModel
+
+## 일반적인 사전 학습 클래스[[generic-pretraining-classes]]
+
+다음 자동 클래스들은 사전 훈련 헤드가 포함된 모델을 인스턴스화하는 데 사용할 수 있습니다.
+
+### AutoModelForPreTraining[[transformers.AutoModelForPreTraining]]
+
+[[autodoc]] AutoModelForPreTraining
+
+### TFAutoModelForPreTraining[[transformers.TFAutoModelForPreTraining]]
+
+[[autodoc]] TFAutoModelForPreTraining
+
+### FlaxAutoModelForPreTraining[[transformers.FlaxAutoModelForPreTraining]]
+
+[[autodoc]] FlaxAutoModelForPreTraining
+
+## 자연어 처리[[natural-language-processing]]
+
+다음 자동 클래스들은 아래의 자연어 처리 작업에 사용할 수 있습니다.
+
+### AutoModelForCausalLM[[transformers.AutoModelForCausalLM]]
+
+[[autodoc]] AutoModelForCausalLM
+
+### TFAutoModelForCausalLM[[transformers.TFAutoModelForCausalLM]]
+
+[[autodoc]] TFAutoModelForCausalLM
+
+### FlaxAutoModelForCausalLM[[transformers.FlaxAutoModelForCausalLM]]
+
+[[autodoc]] FlaxAutoModelForCausalLM
+
+### AutoModelForMaskedLM[[transformers.AutoModelForMaskedLM]]
+
+[[autodoc]] AutoModelForMaskedLM
+
+### TFAutoModelForMaskedLM[[transformers.TFAutoModelForMaskedLM]]
+
+[[autodoc]] TFAutoModelForMaskedLM
+
+### FlaxAutoModelForMaskedLM[[transformers.FlaxAutoModelForMaskedLM]]
+
+[[autodoc]] FlaxAutoModelForMaskedLM
+
+### AutoModelForMaskGeneration[[transformers.AutoModelForMaskGeneration]]
+
+[[autodoc]] AutoModelForMaskGeneration
+
+### TFAutoModelForMaskGeneration[[transformers.TFAutoModelForMaskGeneration]]
+
+[[autodoc]] TFAutoModelForMaskGeneration
+
+### AutoModelForSeq2SeqLM[[transformers.AutoModelForSeq2SeqLM]]
+
+[[autodoc]] AutoModelForSeq2SeqLM
+
+### TFAutoModelForSeq2SeqLM[[transformers.TFAutoModelForSeq2SeqLM]]
+
+[[autodoc]] TFAutoModelForSeq2SeqLM
+
+### FlaxAutoModelForSeq2SeqLM[[transformers.FlaxAutoModelForSeq2SeqLM]]
+
+[[autodoc]] FlaxAutoModelForSeq2SeqLM
+
+### AutoModelForSequenceClassification[[transformers.AutoModelForSequenceClassification]]
+
+[[autodoc]] AutoModelForSequenceClassification
+
+### TFAutoModelForSequenceClassification[[transformers.TFAutoModelForSequenceClassification]]
+
+[[autodoc]] TFAutoModelForSequenceClassification
+
+### FlaxAutoModelForSequenceClassification[[transformers.FlaxAutoModelForSequenceClassification]]
+
+[[autodoc]] FlaxAutoModelForSequenceClassification
+
+### AutoModelForMultipleChoice[[transformers.AutoModelForMultipleChoice]]
+
+[[autodoc]] AutoModelForMultipleChoice
+
+### TFAutoModelForMultipleChoice[[transformers.TFAutoModelForMultipleChoice]]
+
+[[autodoc]] TFAutoModelForMultipleChoice
+
+### FlaxAutoModelForMultipleChoice[[transformers.FlaxAutoModelForMultipleChoice]]
+
+[[autodoc]] FlaxAutoModelForMultipleChoice
+
+### AutoModelForNextSentencePrediction[[transformers.AutoModelForNextSentencePrediction]]
+
+[[autodoc]] AutoModelForNextSentencePrediction
+
+### TFAutoModelForNextSentencePrediction[[transformers.TFAutoModelForNextSentencePrediction]]
+
+[[autodoc]] TFAutoModelForNextSentencePrediction
+
+### FlaxAutoModelForNextSentencePrediction[[transformers.FlaxAutoModelForNextSentencePrediction]]
+
+[[autodoc]] FlaxAutoModelForNextSentencePrediction
+
+### AutoModelForTokenClassification[[transformers.AutoModelForTokenClassification]]
+
+[[autodoc]] AutoModelForTokenClassification
+
+### TFAutoModelForTokenClassification[[transformers.TFAutoModelForTokenClassification]]
+
+[[autodoc]] TFAutoModelForTokenClassification
+
+### FlaxAutoModelForTokenClassification[[transformers.FlaxAutoModelForTokenClassification]]
+
+[[autodoc]] FlaxAutoModelForTokenClassification
+
+### AutoModelForQuestionAnswering[[transformers.AutoModelForQuestionAnswering]]
+
+[[autodoc]] AutoModelForQuestionAnswering
+
+### TFAutoModelForQuestionAnswering[[transformers.TFAutoModelForQuestionAnswering]]
+
+[[autodoc]] TFAutoModelForQuestionAnswering
+
+### FlaxAutoModelForQuestionAnswering[[transformers.FlaxAutoModelForQuestionAnswering]]
+
+[[autodoc]] FlaxAutoModelForQuestionAnswering
+
+### AutoModelForTextEncoding[[transformers.AutoModelForTextEncoding]]
+
+[[autodoc]] AutoModelForTextEncoding
+
+### TFAutoModelForTextEncoding[[transformers.TFAutoModelForTextEncoding]]
+
+[[autodoc]] TFAutoModelForTextEncoding
+
+## 컴퓨터 비전[[computer-vision]]
+
+다음 자동 클래스들은 아래의 컴퓨터 비전 작업에 사용할 수 있습니다.
+
+### AutoModelForDepthEstimation[[transformers.AutoModelForDepthEstimation]]
+
+[[autodoc]] AutoModelForDepthEstimation
+
+### AutoModelForImageClassification[[transformers.AutoModelForImageClassification]]
+
+[[autodoc]] AutoModelForImageClassification
+
+### TFAutoModelForImageClassification[[transformers.TFAutoModelForImageClassification]]
+
+[[autodoc]] TFAutoModelForImageClassification
+
+### FlaxAutoModelForImageClassification[[transformers.FlaxAutoModelForImageClassification]]
+
+[[autodoc]] FlaxAutoModelForImageClassification
+
+### AutoModelForVideoClassification[[transformers.AutoModelForVideoClassification]]
+
+[[autodoc]] AutoModelForVideoClassification
+
+### AutoModelForKeypointDetection[[transformers.AutoModelForKeypointDetection]]
+
+[[autodoc]] AutoModelForKeypointDetection
+
+### AutoModelForMaskedImageModeling[[transformers.AutoModelForMaskedImageModeling]]
+
+[[autodoc]] AutoModelForMaskedImageModeling
+
+### TFAutoModelForMaskedImageModeling[[transformers.TFAutoModelForMaskedImageModeling]]
+
+[[autodoc]] TFAutoModelForMaskedImageModeling
+
+### AutoModelForObjectDetection[[transformers.AutoModelForObjectDetection]]
+
+[[autodoc]] AutoModelForObjectDetection
+
+### AutoModelForImageSegmentation[[transformers.AutoModelForImageSegmentation]]
+
+[[autodoc]] AutoModelForImageSegmentation
+
+### AutoModelForImageToImage[[transformers.AutoModelForImageToImage]]
+
+[[autodoc]] AutoModelForImageToImage
+
+### AutoModelForSemanticSegmentation[[transformers.AutoModelForSemanticSegmentation]]
+
+[[autodoc]] AutoModelForSemanticSegmentation
+
+### TFAutoModelForSemanticSegmentation[[transformers.TFAutoModelForSemanticSegmentation]]
+
+[[autodoc]] TFAutoModelForSemanticSegmentation
+
+### AutoModelForInstanceSegmentation[[transformers.AutoModelForInstanceSegmentation]]
+
+[[autodoc]] AutoModelForInstanceSegmentation
+
+### AutoModelForUniversalSegmentation[[transformers.AutoModelForUniversalSegmentation]]
+
+[[autodoc]] AutoModelForUniversalSegmentation
+
+### AutoModelForZeroShotImageClassification[[transformers.AutoModelForZeroShotImageClassification]]
+
+[[autodoc]] AutoModelForZeroShotImageClassification
+
+### TFAutoModelForZeroShotImageClassification[[transformers.TFAutoModelForZeroShotImageClassification]]
+
+[[autodoc]] TFAutoModelForZeroShotImageClassification
+
+### AutoModelForZeroShotObjectDetection[[transformers.AutoModelForZeroShotObjectDetection]]
+
+[[autodoc]] AutoModelForZeroShotObjectDetection
+
+## 오디오[[audio]]
+
+다음 자동 클래스들은 아래의 오디오 작업에 사용할 수 있습니다.
+
+### AutoModelForAudioClassification[[transformers.AutoModelForAudioClassification]]
+
+[[autodoc]] AutoModelForAudioClassification
+
+### TFAutoModelForAudioClassification[[transformers.TFAutoModelForAudioClassification]]
+
+[[autodoc]] TFAutoModelForAudioClassification
+
+### AutoModelForAudioFrameClassification[[transformers.AutoModelForAudioFrameClassification]]
+
+[[autodoc]] AutoModelForAudioFrameClassification
+
+### AutoModelForCTC[[transformers.AutoModelForCTC]]
+
+[[autodoc]] AutoModelForCTC
+
+### AutoModelForSpeechSeq2Seq[[transformers.AutoModelForSpeechSeq2Seq]]
+
+[[autodoc]] AutoModelForSpeechSeq2Seq
+
+### TFAutoModelForSpeechSeq2Seq[[transformers.TFAutoModelForSpeechSeq2Seq]]
+
+[[autodoc]] TFAutoModelForSpeechSeq2Seq
+
+### FlaxAutoModelForSpeechSeq2Seq[[transformers.FlaxAutoModelForSpeechSeq2Seq]]
+
+[[autodoc]] FlaxAutoModelForSpeechSeq2Seq
+
+### AutoModelForAudioXVector[[transformers.AutoModelForAudioXVector]]
+
+[[autodoc]] AutoModelForAudioXVector
+
+### AutoModelForTextToSpectrogram[[transformers.AutoModelForTextToSpectrogram]]
+
+[[autodoc]] AutoModelForTextToSpectrogram
+
+### AutoModelForTextToWaveform[[transformers.AutoModelForTextToWaveform]]
+
+[[autodoc]] AutoModelForTextToWaveform
+
+## 멀티모달[[multimodal]]
+
+다음 자동 클래스들은 아래의 멀티모달 작업에 사용할 수 있습니다.
+
+### AutoModelForTableQuestionAnswering[[transformers.AutoModelForTableQuestionAnswering]]
+
+[[autodoc]] AutoModelForTableQuestionAnswering
+
+### TFAutoModelForTableQuestionAnswering[[transformers.TFAutoModelForTableQuestionAnswering]]
+
+[[autodoc]] TFAutoModelForTableQuestionAnswering
+
+### AutoModelForDocumentQuestionAnswering[[transformers.AutoModelForDocumentQuestionAnswering]]
+
+[[autodoc]] AutoModelForDocumentQuestionAnswering
+
+### TFAutoModelForDocumentQuestionAnswering[[transformers.TFAutoModelForDocumentQuestionAnswering]]
+
+[[autodoc]] TFAutoModelForDocumentQuestionAnswering
+
+### AutoModelForVisualQuestionAnswering[[transformers.AutoModelForVisualQuestionAnswering]]
+
+[[autodoc]] AutoModelForVisualQuestionAnswering
+
+### AutoModelForVision2Seq[[transformers.AutoModelForVision2Seq]]
+
+[[autodoc]] AutoModelForVision2Seq
+
+### TFAutoModelForVision2Seq[[transformers.TFAutoModelForVision2Seq]]
+
+[[autodoc]] TFAutoModelForVision2Seq
+
+### FlaxAutoModelForVision2Seq[[transformers.FlaxAutoModelForVision2Seq]]
+
+[[autodoc]] FlaxAutoModelForVision2Seq
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/autoformer.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/autoformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..e8534ac95c327ab65a1ccc8a3c3fa67fab446344
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/autoformer.md
@@ -0,0 +1,50 @@
+
+
+# Autoformer[[autoformer]]
+
+## 개요[[overview]]
+
+The Autoformer 모델은 Haixu Wu, Jiehui Xu, Jianmin Wang, Mingsheng Long가 제안한 [오토포머: 장기 시계열 예측을 위한 자기상관 분해 트랜스포머](https://arxiv.org/abs/2106.13008) 라는 논문에서 소개 되었습니다.
+
+이 모델은 트랜스포머를 심층 분해 아키텍처로 확장하여, 예측 과정에서 추세와 계절성 요소를 점진적으로 분해할 수 있습니다.
+
+해당 논문의 초록입니다:
+
+*예측 시간을 연장하는 것은 극한 기상 조기 경보 및 장기 에너지 소비 계획과 같은 실제 응용 프로그램에 중요한 요구 사항입니다. 본 논문은 시계열의 장기 예측 문제를 연구합니다. 기존의 트랜스포머 기반 모델들은 장거리 종속성을 발견하기 위해 다양한 셀프 어텐션 메커니즘을 채택합니다. 그러나 장기 미래의 복잡한 시간적 패턴으로 인해 모델이 신뢰할 수 있는 종속성을 찾기 어렵습니다. 또한, 트랜스포머는 긴 시계열의 효율성을 위해 점별 셀프 어텐션의 희소 버전을 채택해야 하므로 정보 활용의 병목 현상이 발생합니다. 우리는 트랜스포머를 넘어서 자기상관 메커니즘을 갖춘 새로운 분해 아키텍처인 Autoformer를 설계했습니다. 우리는 시계열 분해의 전처리 관행을 깨고 이를 심층 모델의 기본 내부 블록으로 혁신했습니다. 이 설계는 Autoformer에 복잡한 시계열에 대한 점진적 분해 능력을 부여합니다. 또한, 확률 과정 이론에서 영감을 받아 시계열의 주기성을 기반으로 자기상관 메커니즘을 설계했으며, 이는 하위 시계열 수준에서 종속성 발견과 표현 집계를 수행합니다. 자기상관은 효율성과 정확도 면에서 셀프 어텐션를 능가합니다. 장기 예측에서 Autoformer는 에너지, 교통, 경제, 날씨, 질병 등 5가지 실용적 응용 분야를 포괄하는 6개 벤치마크에서 38%의 상대적 개선으로 최첨단 정확도를 달성했습니다.*
+
+이 모델은 [elisim](https://huggingface.co/elisim)과 [kashif](https://huggingface.co/kashif)에 의해 기여 되었습니다.
+원본 코드는 [이곳](https://github.com/thuml/Autoformer)에서 확인할 수 있습니다.
+
+## 자료[[resources]]
+
+시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+- HuggingFace 블로그에서 Autoformer 포스트를 확인하세요: [네, 그렇습니다, 트랜스포머는 시계열 예측에 효과적입니다(+ Autoformer)](https://huggingface.co/blog/autoformer)
+
+## AutoformerConfig[[transformers.AutoformerConfig]]
+
+[[autodoc]] AutoformerConfig
+
+## AutoformerModel[[transformers.AutoformerModel]]
+
+[[autodoc]] AutoformerModel
+ - forward
+
+## AutoformerForPrediction[[transformers.AutoformerForPrediction]]
+
+[[autodoc]] AutoformerForPrediction
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bart.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bart.md
new file mode 100644
index 0000000000000000000000000000000000000000..0f7636b3cc95c284de5eb5a650b6393c6d0c69bf
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bart.md
@@ -0,0 +1,217 @@
+
+
+# BART[[bart]]
+
+
+
+## 개요 [[overview]]
+
+Bart 모델은 2019년 10월 29일 Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov, Luke Zettlemoyer가 발표한 [BART: 자연어 생성, 번역, 이해를 위한 잡음 제거 seq2seq 사전 훈련](https://arxiv.org/abs/1910.13461)이라는 논문에서 소개되었습니다.
+
+논문의 초록에 따르면,
+
+- Bart는 양방향 인코더(BERT와 유사)와 왼쪽에서 오른쪽으로 디코딩하는 디코더(GPT와 유사)를 사용하는 표준 seq2seq/기계 번역 아키텍처를 사용합니다.
+- 사전 훈련 작업은 원래 문장의 순서를 무작위로 섞고, 텍스트의 일부 구간을 단일 마스크 토큰으로 대체하는 새로운 인필링(in-filling) 방식을 포함합니다.
+- BART는 특히 텍스트 생성을 위한 미세 조정에 효과적이지만 이해 작업에도 잘 작동합니다. GLUE와 SQuAD에서 비슷한 훈련 리소스로 RoBERTa의 성능과 일치하며, 추상적 대화, 질의응답, 요약 작업 등에서 최대 6 ROUGE 점수의 향상을 보이며 새로운 최고 성능을 달성했습니다.
+
+이 모델은 [sshleifer](https://huggingface.co/sshleifer)에 의해 기여 되었습니다. 저자의 코드는 [이곳](https://github.com/pytorch/fairseq/tree/master/examples/bart)에서 확인할 수 있습니다.
+
+## 사용 팁:[[usage-tips]]
+
+- BART는 절대 위치 임베딩을 사용하는 모델이므로 일반적으로 입력을 왼쪽보다는 오른쪽에 패딩하는 것이 좋습니다.
+- 인코더와 디코더가 있는 seq2seq 모델입니다. 인코더에는 손상된 토큰이(corrupted tokens) 입력되고, 디코더에는 원래 토큰이 입력됩니다(단, 일반적인 트랜스포머 디코더처럼 미래 단어를 숨기는 마스크가 있습니다). 사전 훈련 작업에서 인코더에 적용되는 변환들의 구성은 다음과 같습니다:
+
+사전 훈련 작업에서 인코더에 적용되는 변환들의 구성은 다음과 같습니다:
+
+ * 무작위 토큰 마스킹 (BERT 처럼)
+ * 무작위 토큰 삭제
+ * k개 토큰의 범위를 단일 마스크 토큰으로 마스킹 (0개 토큰의 범위는 마스크 토큰의 삽입을 의미)
+ * 문장 순서 뒤섞기
+ * 특정 토큰에서 시작하도록 문서 회전
+
+## 구현 노트[[implementation-notes]]
+
+- Bart는 시퀀스 분류에 `token_type_ids`를 사용하지 않습니다. 적절하게 나누기 위해서 [`BartTokenizer`]나
+ [`~BartTokenizer.encode`]를 사용합니다.
+- [`BartModel`]의 정방향 전달은 `decoder_input_ids`가 전달되지 않으면 `decoder_input_ids`를 자동으로 생성할 것입니다. 이는 다른 일부 모델링 API와 다른 점입니다. 이 기능의 일반적인 사용 사례는 마스크 채우기(mask filling)입니다.
+- 모델 예측은 `forced_bos_token_id=0`일 때 기존 구현과 동일하게 작동하도록 의도되었습니다. 하지만, [`fairseq.encode`]에 전달하는 문자열이 공백으로 시작할 때만 이 기능이 작동합니다.
+- [`~generation.GenerationMixin.generate`]는 요약과 같은 조건부 생성 작업에 사용되어야 합니다. 자세한 내용은 해당 문서의 예제를 참조하세요.
+- *facebook/bart-large-cnn* 가중치를 로드하는 모델은 `mask_token_id`가 없거나, 마스크 채우기 작업을 수행할 수 없습니다.
+
+## 마스크 채우기[[mask-filling]]
+
+`facebook/bart-base`와 `facebook/bart-large` 체크포인트는 멀티 토큰 마스크를 채우는데 사용될 수 있습니다.
+
+```python
+from transformers import BartForConditionalGeneration, BartTokenizer
+
+model = BartForConditionalGeneration.from_pretrained("facebook/bart-large", forced_bos_token_id=0)
+tok = BartTokenizer.from_pretrained("facebook/bart-large")
+example_english_phrase = "UN Chief Says There Is No in Syria"
+batch = tok(example_english_phrase, return_tensors="pt")
+generated_ids = model.generate(batch["input_ids"])
+assert tok.batch_decode(generated_ids, skip_special_tokens=True) == [
+ "UN Chief Says There Is No Plan to Stop Chemical Weapons in Syria"
+]
+```
+
+## 자료[[resources]]
+
+BART를 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+
+
+- [분산형 학습: 🤗 Transformers와 Amazon SageMaker를 이용하여 요약하기 위한 BART/T5 학습](https://huggingface.co/blog/sagemaker-distributed-training-seq2seq)에 대한 블로그 포스트.
+- [blurr를 이용하여 fastai로 요약하기 위한 BART를 미세 조정](https://colab.research.google.com/github/ohmeow/ohmeow_website/blob/master/posts/2021-05-25-mbart-sequence-classification-with-blurr.ipynb)하는 방법에 대한 노트북. 🌎
+- [Trainer 클래스를 사용하여 두 가지 언어로 요약하기 위한 BART 미세 조정](https://colab.research.google.com/github/elsanns/xai-nlp-notebooks/blob/master/fine_tune_bart_summarization_two_langs.ipynb)하는 방법에 대한 노트북. 🌎
+- 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization.ipynb)에서는 [`BartForConditionalGeneration`]이 지원됩니다.
+- [`TFBartForConditionalGeneration`]는 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/summarization)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization-tf.ipynb)에서 지원됩니다.
+- 이 [예제 스크립트에서는](https://github.com/huggingface/transformers/tree/main/examples/flax/summarization)[`FlaxBartForConditionalGeneration`]이 지원됩니다.
+- Hugging Face `datasets` 객체를 활용하여 [`BartForConditionalGeneration`]을 학습시키는 방법의 예는 이 [포럼 토론](https://discuss.huggingface.co/t/train-bart-for-conditional-generation-e-g-summarization/1904)에서 찾을 수 있습니다.
+- 🤗 Hugging Face 코스의 [요약](https://huggingface.co/course/chapter7/5?fw=pt#summarization)장.
+- [요약 작업 가이드](../tasks/summarization)
+
+
+
+- [`BartForConditionalGeneration`]는 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/language-modeling#robertabertdistilbert-and-masked-language-modeling)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)을 참고하세요.
+- [`TFBartForConditionalGeneration`]는 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/language-modeling#run_mlmpy)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)을 참고하세요.
+- [`FlaxBartForConditionalGeneration`]는 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/flax/language-modeling#masked-language-modeling)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/masked_language_modeling_flax.ipynb)을 참고 하세요.
+- 🤗 Hugging Face 코스의 [마스크 언어 모델링](https://huggingface.co/course/chapter7/3?fw=pt) 챕터.
+- [마스크 언어 모델링 작업 가이드](../tasks/masked_language_modeling)
+
+
+
+- [Seq2SeqTrainer를 이용하여 인도어를 영어로 번역하는 mBART를 미세 조정](https://colab.research.google.com/github/vasudevgupta7/huggingface-tutorials/blob/main/translation_training.ipynb)하는 방법에 대한 가이드. 🌎
+- [`BartForConditionalGeneration`]는 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/translation)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation.ipynb)을 참고하세요.
+- [`TFBartForConditionalGeneration`]는 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/translation)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation-tf.ipynb)을 참고 하세요.
+- [번역 작업 가이드](../tasks/translation)
+
+추가적으로 볼 것들:
+- [텍스트 분류 작업 가이드](../tasks/sequence_classification)
+- [질문 답변 작업 가이드](../tasks/question_answering)
+- [인과적 언어 모델링 작업 가이드](../tasks/language_modeling)
+- 이 [논문](https://arxiv.org/abs/2010.13002)은 [증류된 체크포인트](https://huggingface.co/models?search=distilbart)에 대해 설명합니다.
+
+## BartConfig[[transformers.BartConfig]]
+
+[[autodoc]] BartConfig
+ - all
+
+## BartTokenizer[[transformers.BartTokenizer]]
+
+[[autodoc]] BartTokenizer
+ - all
+
+## BartTokenizerFast[[transformers.BartTokenizerFast]]
+
+[[autodoc]] BartTokenizerFast
+ - all
+
+
+
+
+
+## BartModel[[transformers.BartModel]]
+
+[[autodoc]] BartModel
+ - forward
+
+## BartForConditionalGeneration[[transformers.BartForConditionalGeneration]]
+
+[[autodoc]] BartForConditionalGeneration
+ - forward
+
+## BartForSequenceClassification[[transformers.BartForSequenceClassification]]
+
+[[autodoc]] BartForSequenceClassification
+ - forward
+
+## BartForQuestionAnswering[[transformers.BartForQuestionAnswering]]
+
+[[autodoc]] BartForQuestionAnswering
+ - forward
+
+## BartForCausalLM[[transformers.BartForCausalLM]]
+
+[[autodoc]] BartForCausalLM
+ - forward
+
+
+
+
+## TFBartModel[[transformers.TFBartModel]]
+
+[[autodoc]] TFBartModel
+ - call
+
+## TFBartForConditionalGeneration[[transformers.TFBartForConditionalGeneration]]
+
+[[autodoc]] TFBartForConditionalGeneration
+ - call
+
+## TFBartForSequenceClassification[[transformers.TFBartForSequenceClassification]]
+
+[[autodoc]] TFBartForSequenceClassification
+ - call
+
+
+
+
+## FlaxBartModel[[transformers.FlaxBartModel]]
+
+[[autodoc]] FlaxBartModel
+ - __call__
+ - encode
+ - decode
+
+## FlaxBartForConditionalGeneration[[transformers.FlaxBartForConditionalGeneration]]
+
+[[autodoc]] FlaxBartForConditionalGeneration
+ - __call__
+ - encode
+ - decode
+
+## FlaxBartForSequenceClassification[[transformers.FlaxBartForSequenceClassification]]
+
+[[autodoc]] FlaxBartForSequenceClassification
+ - __call__
+ - encode
+ - decode
+
+## FlaxBartForQuestionAnswering[[transformers.FlaxBartForQuestionAnswering]]
+
+[[autodoc]] FlaxBartForQuestionAnswering
+ - __call__
+ - encode
+ - decode
+
+## FlaxBartForCausalLM[[transformers.FlaxBartForCausalLM]]
+
+[[autodoc]] FlaxBartForCausalLM
+ - __call__
+
+
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/barthez.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/barthez.md
new file mode 100644
index 0000000000000000000000000000000000000000..131db38856cc1b253a6cbdaa6e3d45de9197de1c
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/barthez.md
@@ -0,0 +1,60 @@
+
+
+# BARThez [[barthez]]
+
+## 개요 [[overview]]
+
+BARThez 모델은 2020년 10월 23일, Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis에 의해 [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321)에서 제안되었습니다.
+
+이 논문의 초록:
+
+
+*자기지도 학습에 의해 가능해진 귀납적 전이 학습은 자연어 처리(NLP) 분야 전반에 걸쳐 큰 반향을 일으켰으며,
+BERT와 BART와 같은 모델들은 수많은 자연어 이해 작업에서 새로운 최첨단 성과를 기록했습니다. 일부 주목할 만한 예외가 있지만,
+대부분의 사용 가능한 모델과 연구는 영어에 집중되어 있었습니다. 본 연구에서는 BARThez를 소개합니다.
+이는 (우리가 아는 한) 프랑스어를 위한 첫 번째 BART 모델입니다.
+BARThez는 과거 연구에서 얻은 매우 큰 프랑스어 단일 언어 말뭉치로 사전훈련되었으며,
+BART의 변형 방식에 맞게 조정되었습니다.
+CamemBERT 및 FlauBERT와 같은 기존의 BERT 기반 프랑스어 모델과 달리, BARThez는 생성 작업에 특히 적합합니다.
+이는 인코더뿐만 아니라 디코더도 사전훈련되었기 때문입니다.
+우리는 FLUE 벤치마크에서의 판별 작업 외에도 이 논문과 함께 공개하는 새로운 요약 데이터셋인 OrangeSum에서 BARThez를 평가했습니다.
+또한 이미 사전훈련된 다국어 BART의 사전훈련을 BARThez의 말뭉치로 계속 진행하였으며,
+결과적으로 얻어진 모델인 mBARTHez가 기본 BARThez보다 유의미한 성능 향상을 보였고,
+CamemBERT 및 FlauBERT와 동등하거나 이를 능가함을 보였습니다.*
+
+이 모델은 [moussakam](https://huggingface.co/moussakam)이 기여했습니다. 저자의 코드는 [여기](https://github.com/moussaKam/BARThez)에서 찾을 수 있습니다.
+
+
+
+BARThez 구현은 🤗 BART와 동일하나, 토큰화에서 차이가 있습니다. 구성 클래스와 그 매개변수에 대한 정보는 [BART 문서](bart)를 참조하십시오.
+BARThez 전용 토크나이저는 아래에 문서화되어 있습니다.
+
+
+
+## 리소스 [[resources]]
+
+- BARThez는 🤗 BART와 유사한 방식으로 시퀀스-투-시퀀스 작업에 맞춰 미세 조정될 수 있습니다. 다음을 확인하세요:
+ [examples/pytorch/summarization/](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization/README.md).
+
+
+## BarthezTokenizer [[bartheztokenizer]]
+
+[[autodoc]] BarthezTokenizer
+
+## BarthezTokenizerFast [[bartheztokenizerfast]]
+
+[[autodoc]] BarthezTokenizerFast
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bartpho.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bartpho.md
new file mode 100644
index 0000000000000000000000000000000000000000..a323c28152c5d9969cee4b08b9dd21a8cb9ab999
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bartpho.md
@@ -0,0 +1,86 @@
+
+
+# BARTpho [[bartpho]]
+
+## 개요 [[overview]]
+
+BARTpho 모델은 Nguyen Luong Tran, Duong Minh Le, Dat Quoc Nguyen에 의해 [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701)에서 제안되었습니다.
+
+이 논문의 초록은 다음과 같습니다:
+
+*우리는 BARTpho_word와 BARTpho_syllable의 두 가지 버전으로 BARTpho를 제시합니다.
+이는 베트남어를 위해 사전훈련된 최초의 대규모 단일 언어 시퀀스-투-시퀀스 모델입니다.
+우리의 BARTpho는 시퀀스-투-시퀀스 디노이징 모델인 BART의 "large" 아키텍처와 사전훈련 방식을 사용하여, 생성형 NLP 작업에 특히 적합합니다.
+베트남어 텍스트 요약의 다운스트림 작업 실험에서,
+자동 및 인간 평가 모두에서 BARTpho가 강력한 기준인 mBART를 능가하고 최신 성능을 개선했음을 보여줍니다.
+우리는 향후 연구 및 베트남어 생성형 NLP 작업의 응용을 촉진하기 위해 BARTpho를 공개합니다.*
+
+이 모델은 [dqnguyen](https://huggingface.co/dqnguyen)이 기여했습니다. 원본 코드는 [여기](https://github.com/VinAIResearch/BARTpho)에서 찾을 수 있습니다.
+
+## 사용 예시 [[usage-example]]
+
+```python
+>>> import torch
+>>> from transformers import AutoModel, AutoTokenizer
+
+>>> bartpho = AutoModel.from_pretrained("vinai/bartpho-syllable")
+
+>>> tokenizer = AutoTokenizer.from_pretrained("vinai/bartpho-syllable")
+
+>>> line = "Chúng tôi là những nghiên cứu viên."
+
+>>> input_ids = tokenizer(line, return_tensors="pt")
+
+>>> with torch.no_grad():
+... features = bartpho(**input_ids) # 이제 모델 출력은 튜플입니다
+
+>>> # With TensorFlow 2.0+:
+>>> from transformers import TFAutoModel
+
+>>> bartpho = TFAutoModel.from_pretrained("vinai/bartpho-syllable")
+>>> input_ids = tokenizer(line, return_tensors="tf")
+>>> features = bartpho(**input_ids)
+```
+
+## 사용 팁 [[usage-tips]]
+
+- mBART를 따르며, BARTpho는 BART의 "large" 아키텍처에 인코더와 디코더의 상단에 추가적인 레이어 정규화 레이어를 사용합니다.
+따라서 [BART 문서](bart)에 있는 사용 예시를 BARTpho에 맞게 적용하려면
+BART 전용 클래스를 mBART 전용 클래스로 대체하여 조정해야 합니다.
+예를 들어:
+
+```python
+>>> from transformers import MBartForConditionalGeneration
+
+>>> bartpho = MBartForConditionalGeneration.from_pretrained("vinai/bartpho-syllable")
+>>> TXT = "Chúng tôi là nghiên cứu viên."
+>>> input_ids = tokenizer([TXT], return_tensors="pt")["input_ids"]
+>>> logits = bartpho(input_ids).logits
+>>> masked_index = (input_ids[0] == tokenizer.mask_token_id).nonzero().item()
+>>> probs = logits[0, masked_index].softmax(dim=0)
+>>> values, predictions = probs.topk(5)
+>>> print(tokenizer.decode(predictions).split())
+```
+
+- 이 구현은 토큰화만을 위한 것입니다: "monolingual_vocab_file"은 다국어
+ XLM-RoBERTa에서 제공되는 사전훈련된 SentencePiece 모델
+ "vocab_file"에서 추출된 베트남어 전용 유형으로 구성됩니다.
+ 다른 언어들도 이 사전훈련된 다국어 SentencePiece 모델 "vocab_file"을 하위 단어 분할에 사용하면, 자신의 언어 전용 "monolingual_vocab_file"과 함께 BartphoTokenizer를 재사용할 수 있습니다.
+
+## BartphoTokenizer [[bartphotokenizer]]
+
+[[autodoc]] BartphoTokenizer
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bert-japanese.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bert-japanese.md
new file mode 100644
index 0000000000000000000000000000000000000000..8c21ef3558908e76288f670cf57d97252775252f
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bert-japanese.md
@@ -0,0 +1,79 @@
+
+
+# 일본어 BERT (BertJapanese) [[bertjapanese]]
+
+## 개요 [[overview]]
+
+일본어 문장에 학습된 BERT 모델 입니다.
+
+각각 서로 다른 토큰화 방법을 사용하는 두 모델:
+
+- MeCab와 WordPiece를 사용하여 토큰화합니다. 이를 위해 추가 의존성 [fugashi](https://github.com/polm/fugashi)이 필요합니다. (이는 [MeCab](https://taku910.github.io/mecab/)의 래퍼입니다.)
+- 문자 단위로 토큰화합니다.
+
+*MecabTokenizer*를 사용하려면, 의존성을 설치하기 위해 `pip install transformers["ja"]` (또는 소스에서 설치하는 경우 `pip install -e .["ja"]`) 명령을 실행해야 합니다.
+
+자세한 내용은 [cl-tohoku 리포지토리](https://github.com/cl-tohoku/bert-japanese)에서 확인하세요.
+
+MeCab과 WordPiece 토큰화를 사용하는 모델 예시:
+
+```python
+>>> import torch
+>>> from transformers import AutoModel, AutoTokenizer
+
+>>> bertjapanese = AutoModel.from_pretrained("cl-tohoku/bert-base-japanese")
+>>> tokenizer = AutoTokenizer.from_pretrained("cl-tohoku/bert-base-japanese")
+
+>>> ## Input Japanese Text
+>>> line = "吾輩は猫である。"
+
+>>> inputs = tokenizer(line, return_tensors="pt")
+
+>>> print(tokenizer.decode(inputs["input_ids"][0]))
+[CLS] 吾輩 は 猫 で ある 。 [SEP]
+
+>>> outputs = bertjapanese(**inputs)
+```
+
+문자 토큰화를 사용하는 모델 예시:
+
+```python
+>>> bertjapanese = AutoModel.from_pretrained("cl-tohoku/bert-base-japanese-char")
+>>> tokenizer = AutoTokenizer.from_pretrained("cl-tohoku/bert-base-japanese-char")
+
+>>> ## Input Japanese Text
+>>> line = "吾輩は猫である。"
+
+>>> inputs = tokenizer(line, return_tensors="pt")
+
+>>> print(tokenizer.decode(inputs["input_ids"][0]))
+[CLS] 吾 輩 は 猫 で あ る 。 [SEP]
+
+>>> outputs = bertjapanese(**inputs)
+```
+
+
+
+이는 토큰화 방법을 제외하고는 BERT와 동일합니다. API 참조 정보는 [BERT 문서](https://huggingface.co/docs/transformers/main/en/model_doc/bert)를 참조하세요.
+이 모델은 [cl-tohoku](https://huggingface.co/cl-tohoku)께서 기여하였습니다.
+
+
+
+
+## BertJapaneseTokenizer
+
+[[autodoc]] BertJapaneseTokenizer
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bert.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bert.md
new file mode 100644
index 0000000000000000000000000000000000000000..531d3e3dd6394766531b64adacf280d6392576c4
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bert.md
@@ -0,0 +1,340 @@
+
+
+# BERT[[BERT]]
+
+
+
+## 개요[[Overview]]
+
+BERT 모델은 Jacob Devlin. Ming-Wei Chang, Kenton Lee, Kristina Touranova가 제안한 논문 [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805)에서 소개되었습니다. BERT는 사전 학습된 양방향 트랜스포머로, Toronto Book Corpus와 Wikipedia로 구성된 대규모 코퍼스에서 마스킹된 언어 모델링과 다음 문장 예측(Next Sentence Prediction) 목표를 결합해 학습되었습니다.
+
+해당 논문의 초록입니다:
+
+*우리는 BERT(Bidirectional Encoder Representations from Transformers)라는 새로운 언어 표현 모델을 소개합니다. 최근의 다른 언어 표현 모델들과 달리, BERT는 모든 계층에서 양방향으로 양쪽 문맥을 조건으로 사용하여 비지도 학습된 텍스트에서 깊이 있는 양방향 표현을 사전 학습하도록 설계되었습니다. 그 결과, 사전 학습된 BERT 모델은 추가적인 출력 계층 하나만으로 질문 응답, 언어 추론과 같은 다양한 작업에서 미세 조정될 수 있으므로, 특정 작업을 위해 아키텍처를 수정할 필요가 없습니다.*
+
+*BERT는 개념적으로 단순하면서도 실증적으로 강력한 모델입니다. BERT는 11개의 자연어 처리 과제에서 새로운 최고 성능을 달성했으며, GLUE 점수를 80.5% (7.7% 포인트 절대 개선)로, MultiNLI 정확도를 86.7% (4.6% 포인트 절대 개선), SQuAD v1.1 질문 응답 테스트에서 F1 점수를 93.2 (1.5% 포인트 절대 개선)로, SQuAD v2.0에서 F1 점수를 83.1 (5.1% 포인트 절대 개선)로 향상시켰습니다.*
+
+이 모델은 [thomwolf](https://huggingface.co/thomwolf)가 기여하였습니다. 원본 코드는 [여기](https://github.com/google-research/bert)에서 확인할 수 있습니다.
+
+## 사용 팁[[Usage tips]]
+
+- BERT는 절대 위치 임베딩을 사용하는 모델이므로 입력을 왼쪽이 아니라 오른쪽에서 패딩하는 것이 일반적으로 권장됩니다.
+- BERT는 마스킹된 언어 모델(MLM)과 Next Sentence Prediction(NSP) 목표로 학습되었습니다. 이는 마스킹된 토큰 예측과 전반적인 자연어 이해(NLU)에 뛰어나지만, 텍스트 생성에는 최적화되어있지 않습니다.
+- BERT의 사전 학습 과정에서는 입력 데이터를 무작위로 마스킹하여 일부 토큰을 마스킹합니다. 전체 토큰 중 약 15%가 다음과 같은 방식으로 마스킹됩니다:
+
+ * 80% 확률로 마스크 토큰으로 대체
+ * 10% 확률로 임의의 다른 토큰으로 대체
+ * 10% 확률로 원래 토큰 그대로 유지
+
+- 모델의 주요 목표는 원본 문장을 예측하는 것이지만, 두 번째 목표가 있습니다: 입력으로 문장 A와 B (사이에는 구분 토큰이 있음)가 주어집니다. 이 문장 쌍이 연속될 확률은 50%이며, 나머지 50%는 서로 무관한 문장들입니다. 모델은 이 두 문장이 아닌지를 예측해야 합니다.
+
+### Scaled Dot Product Attention(SDPA) 사용하기 [[Using Scaled Dot Product Attention (SDPA)]]
+
+Pytorch는 `torch.nn.functional`의 일부로 Scaled Dot Product Attention(SDPA) 연산자를 기본적으로 제공합니다. 이 함수는 입력과 하드웨어에 따라 여러 구현 방식을 사용할 수 있습니다. 자세한 내용은 [공식 문서](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)나 [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)에서 확인할 수 있습니다.
+
+`torch>=2.1.1`에서는 구현이 가능한 경우 SDPA가 기본적으로 사용되지만, `from_pretrained()`함수에서 `attn_implementation="sdpa"`를 설정하여 SDPA를 명시적으로 사용하도록 지정할 수도 있습니다.
+
+```
+from transformers import BertModel
+
+model = BertModel.from_pretrained("bert-base-uncased", torch_dtype=torch.float16, attn_implementation="sdpa")
+...
+```
+
+최적 성능 향상을 위해 모델을 반정밀도(예: `torch.float16` 또는 `torch.bfloat16`)로 불러오는 것을 권장합니다.
+
+로컬 벤치마크 (A100-80GB, CPUx12, RAM 96.6GB, PyTorch 2.2.0, OS Ubuntu 22.04)에서 `float16`을 사용해 학습 및 추론을 수행한 결과, 다음과 같은 속도 향상이 관찰되었습니다.
+
+#### 학습 [[Training]]
+
+|batch_size|seq_len|Time per batch (eager - s)|Time per batch (sdpa - s)|Speedup (%)|Eager peak mem (MB)|sdpa peak mem (MB)|Mem saving (%)|
+|----------|-------|--------------------------|-------------------------|-----------|-------------------|------------------|--------------|
+|4 |256 |0.023 |0.017 |35.472 |939.213 |764.834 |22.800 |
+|4 |512 |0.023 |0.018 |23.687 |1970.447 |1227.162 |60.569 |
+|8 |256 |0.023 |0.018 |23.491 |1594.295 |1226.114 |30.028 |
+|8 |512 |0.035 |0.025 |43.058 |3629.401 |2134.262 |70.054 |
+|16 |256 |0.030 |0.024 |25.583 |2874.426 |2134.262 |34.680 |
+|16 |512 |0.064 |0.044 |46.223 |6964.659 |3961.013 |75.830 |
+
+#### 추론 [[Inference]]
+
+|batch_size|seq_len|Per token latency eager (ms)|Per token latency SDPA (ms)|Speedup (%)|Mem eager (MB)|Mem BT (MB)|Mem saved (%)|
+|----------|-------|----------------------------|---------------------------|-----------|--------------|-----------|-------------|
+|1 |128 |5.736 |4.987 |15.022 |282.661 |282.924 |-0.093 |
+|1 |256 |5.689 |4.945 |15.055 |298.686 |298.948 |-0.088 |
+|2 |128 |6.154 |4.982 |23.521 |314.523 |314.785 |-0.083 |
+|2 |256 |6.201 |4.949 |25.303 |347.546 |347.033 |0.148 |
+|4 |128 |6.049 |4.987 |21.305 |378.895 |379.301 |-0.107 |
+|4 |256 |6.285 |5.364 |17.166 |443.209 |444.382 |-0.264 |
+
+
+
+## 자료[[Resources]]
+
+BERT를 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+
+
+- [BERT 텍스트 분류 (다른 언어로)](https://www.philschmid.de/bert-text-classification-in-a-different-language)에 대한 블로그 포스트.
+- [다중 레이블 텍스트 분류를 위한 BERT (및 관련 모델) 미세 조정](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/BERT/Fine_tuning_BERT_(and_friends)_for_multi_label_text_classification.ipynb)에 대한 노트북.
+- [PyTorch를 이용해 BERT를 다중 레이블 분류를 위해 미세 조정하는 방법](htt기ps://colab.research.google.com/github/abhimishra91/transformers-tutorials/blob/master/transformers_multi_label_classification.ipynb)에 대한 노트북. 🌎
+- [BERT로 EncoderDecoder 모델을 warm-start하여 요약하기](https://colab.research.google.com/github/patrickvonplaten/notebooks/blob/master/BERT2BERT_for_CNN_Dailymail.ipynb)에 대한 노트북.
+- [`BertForSequenceClassification`]이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-classification)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb)에서 지원됩니다.
+- [`TFBertForSequenceClassification`]이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/text-classification)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification-tf.ipynb)에서 지원됩니다.
+- [`FlaxBertForSequenceClassification`]이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/flax/text-classification)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification_flax.ipynb)에서 지원됩니다.
+- [텍스트 분류 작업 가이드](../tasks/sequence_classification)
+
+
+
+- [Keras와 함께 Hugging Face Transformers를 사용하여 비영리 BERT를 개체명 인식(NER)용으로 미세 조정하는 방법](https://www.philschmid.de/huggingface-transformers-keras-tf)에 대한 블로그 포스트.
+- [BERT를 개체명 인식을 위해 미세 조정하기](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/BERT/Custom_Named_Entity_Recognition_with_BERT_only_first_wordpiece.ipynb)에 대한 노트북. 각 단어의 첫 번째 wordpiece에만 레이블을 지정하여 학습하는 방법을 설명합니다. 모든 wordpiece에 레이블을 전파하는 방법은 [이 버전](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/BERT/Custom_Named_Entity_Recognition_with_BERT.ipynb)에서 확인할 수 있습니다.
+- [`BertForTokenClassification`]이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/token-classification)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb)에서 지원됩니다.
+- [`TFBertForTokenClassification`]이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/token-classification)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification-tf.ipynb)에서 지원됩니다.
+- [`FlaxBertForTokenClassification`]이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/flax/token-classification)에서 지원됩니다.
+- 🤗 Hugging Face 코스의 [토큰 분류 챕터](https://huggingface.co/course/chapter7/2?fw=pt).
+- [토큰 분류 작업 가이드](../tasks/token_classification)
+
+
+
+- [`BertForMaskedLM`]이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/language-modeling#robertabertdistilbert-and-masked-language-modeling)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)에서 지원됩니다.
+- [`TFBertForMaskedLM`]이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/language-modeling#run_mlmpy) 와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)에서 지원됩니다.
+- [`FlaxBertForMaskedLM`]이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/flax/language-modeling#masked-language-modeling)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/masked_language_modeling_flax.ipynb)에서 지원됩니다.
+- 🤗 Hugging Face 코스의 [마스킹된 언어 모델링 챕터](https://huggingface.co/course/chapter7/3?fw=pt).
+- [마스킹된 언어 모델링 작업 가이드](../tasks/masked_language_modeling)
+
+
+
+- [`BertForQuestionAnswering`]이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb)에서 지원됩니다.
+- [`TFBertForQuestionAnswering`]이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/question-answering) 와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering-tf.ipynb)에서 지원됩니다.
+- [`FlaxBertForQuestionAnswering`]이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/flax/question-answering)에서 지원됩니다.
+- 🤗 Hugging Face 코스의 [질문 답변 챕터](https://huggingface.co/course/chapter7/7?fw=pt).
+- [질문 답변 작업 가이드](../tasks/question_answering)
+
+**다중 선택**
+- [`BertForMultipleChoice`]이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/multiple-choice)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice.ipynb)에서 지원됩니다.
+- [`TFBertForMultipleChoice`]이 [에제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/multiple-choice)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice-tf.ipynb)에서 지원됩니다.
+- [다중 선택 작업 가이드](../tasks/multiple_choice)
+
+⚡️ **추론**
+- [Hugging Face Transformers와 AWS Inferentia를 사용하여 BERT 추론을 가속화하는 방법](https://huggingface.co/blog/bert-inferentia-sagemaker)에 대한 블로그 포스트.
+- [GPU에서 DeepSpeed-Inference로 BERT 추론을 가속화하는 방법](https://www.philschmid.de/bert-deepspeed-inference)에 대한 블로그 포스트.
+
+⚙️ **사전 학습**
+- [Hugging Face Optimum으로 Transformers를 ONMX로 변환하는 방법](https://www.philschmid.de/pre-training-bert-habana)에 대한 블로그 포스트.
+
+🚀 **배포**
+- [Hugging Face Optimum으로 Transformers를 ONMX로 변환하는 방법](https://www.philschmid.de/convert-transformers-to-onnx)에 대한 블로그 포스트.
+- [AWS에서 Hugging Face Transformers를 위한 Habana Gaudi 딥러닝 환경 설정 방법](https://www.philschmid.de/getting-started-habana-gaudi#conclusion)에 대한 블로그 포스트.
+- [Hugging Face Transformers, Amazon SageMaker 및 Terraform 모듈을 이용한 BERT 자동 확장](https://www.philschmid.de/terraform-huggingface-amazon-sagemaker-advanced)에 대한 블로그 포스트.
+- [Hugging Face, AWS Lambda, Docker를 활용하여 서버리스 BERT 설정하는 방법](https://www.philschmid.de/serverless-bert-with-huggingface-aws-lambda-docker)에 대한 블로그 포스트.
+- [Amazon SageMaker와 Training Compiler를 사용하여 Hugging Face Transformers에서 BERT 미세 조정하는 방법](https://www.philschmid.de/huggingface-amazon-sagemaker-training-compiler)에 대한 블로그.
+- [Amazon SageMaker를 사용한 Transformers와 BERT의 작업별 지식 증류](https://www.philschmid.de/knowledge-distillation-bert-transformers)에 대한 블로그 포스트.
+
+## BertConfig
+
+[[autodoc]] BertConfig
+ - all
+
+## BertTokenizer
+
+[[autodoc]] BertTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+
+
+
+## BertTokenizerFast
+
+[[autodoc]] BertTokenizerFast
+
+
+
+
+## TFBertTokenizer
+
+[[autodoc]] TFBertTokenizer
+
+
+
+
+## Bert specific outputs
+
+[[autodoc]] models.bert.modeling_bert.BertForPreTrainingOutput
+
+[[autodoc]] models.bert.modeling_tf_bert.TFBertForPreTrainingOutput
+
+[[autodoc]] models.bert.modeling_flax_bert.FlaxBertForPreTrainingOutput
+
+
+
+
+
+## BertModel
+
+[[autodoc]] BertModel
+ - forward
+
+## BertForPreTraining
+
+[[autodoc]] BertForPreTraining
+ - forward
+
+## BertLMHeadModel
+
+[[autodoc]] BertLMHeadModel
+ - forward
+
+## BertForMaskedLM
+
+[[autodoc]] BertForMaskedLM
+ - forward
+
+## BertForNextSentencePrediction
+
+[[autodoc]] BertForNextSentencePrediction
+ - forward
+
+## BertForSequenceClassification
+
+[[autodoc]] BertForSequenceClassification
+ - forward
+
+## BertForMultipleChoice
+
+[[autodoc]] BertForMultipleChoice
+ - forward
+
+## BertForTokenClassification
+
+[[autodoc]] BertForTokenClassification
+ - forward
+
+## BertForQuestionAnswering
+
+[[autodoc]] BertForQuestionAnswering
+ - forward
+
+
+
+
+## TFBertModel
+
+[[autodoc]] TFBertModel
+ - call
+
+## TFBertForPreTraining
+
+[[autodoc]] TFBertForPreTraining
+ - call
+
+## TFBertModelLMHeadModel
+
+[[autodoc]] TFBertLMHeadModel
+ - call
+
+## TFBertForMaskedLM
+
+[[autodoc]] TFBertForMaskedLM
+ - call
+
+## TFBertForNextSentencePrediction
+
+[[autodoc]] TFBertForNextSentencePrediction
+ - call
+
+## TFBertForSequenceClassification
+
+[[autodoc]] TFBertForSequenceClassification
+ - call
+
+## TFBertForMultipleChoice
+
+[[autodoc]] TFBertForMultipleChoice
+ - call
+
+## TFBertForTokenClassification
+
+[[autodoc]] TFBertForTokenClassification
+ - call
+
+## TFBertForQuestionAnswering
+
+[[autodoc]] TFBertForQuestionAnswering
+ - call
+
+
+
+
+## FlaxBertModel
+
+[[autodoc]] FlaxBertModel
+ - __call__
+
+## FlaxBertForPreTraining
+
+[[autodoc]] FlaxBertForPreTraining
+ - __call__
+
+## FlaxBertForCausalLM
+
+[[autodoc]] FlaxBertForCausalLM
+ - __call__
+
+## FlaxBertForMaskedLM
+
+[[autodoc]] FlaxBertForMaskedLM
+ - __call__
+
+## FlaxBertForNextSentencePrediction
+
+[[autodoc]] FlaxBertForNextSentencePrediction
+ - __call__
+
+## FlaxBertForSequenceClassification
+
+[[autodoc]] FlaxBertForSequenceClassification
+ - __call__
+
+## FlaxBertForMultipleChoice
+
+[[autodoc]] FlaxBertForMultipleChoice
+ - __call__
+
+## FlaxBertForTokenClassification
+
+[[autodoc]] FlaxBertForTokenClassification
+ - __call__
+
+## FlaxBertForQuestionAnswering
+
+[[autodoc]] FlaxBertForQuestionAnswering
+ - __call__
+
+
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bertweet.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bertweet.md
new file mode 100644
index 0000000000000000000000000000000000000000..7a46087d0a8ebf85929aadbb74808ffe029537c9
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/bertweet.md
@@ -0,0 +1,67 @@
+
+
+# BERTweet [[bertweet]]
+
+## 개요 [[overview]]
+
+BERTweet 모델은 Dat Quoc Nguyen, Thanh Vu, Anh Tuan Nguyen에 의해 [BERTweet: A pre-trained language model for English Tweets](https://www.aclweb.org/anthology/2020.emnlp-demos.2.pdf) 에서 제안되었습니다.
+
+해당 논문의 초록 :
+
+*영어 트윗을 위한 최초의 공개 대규모 사전 학습된 언어 모델인 BERTweet을 소개합니다.
+BERTweet은 BERT-base(Devlin et al., 2019)와 동일한 아키텍처를 가지고 있으며, RoBERTa 사전 학습 절차(Liu et al., 2019)를 사용하여 학습되었습니다.
+실험 결과, BERTweet은 강력한 기준 모델인 RoBERTa-base 및 XLM-R-base(Conneau et al., 2020)의 성능을 능가하여 세 가지 트윗 NLP 작업(품사 태깅, 개체명 인식, 텍스트 분류)에서 이전 최신 모델보다 더 나은 성능을 보여주었습니다.*
+
+이 모델은 [dqnguyen](https://huggingface.co/dqnguyen) 께서 기여하셨습니다. 원본 코드는 [여기](https://github.com/VinAIResearch/BERTweet).에서 확인할 수 있습니다.
+
+
+## 사용 예시 [[usage-example]]
+
+```python
+>>> import torch
+>>> from transformers import AutoModel, AutoTokenizer
+
+>>> bertweet = AutoModel.from_pretrained("vinai/bertweet-base")
+
+>>> # 트랜스포머 버전 4.x 이상 :
+>>> tokenizer = AutoTokenizer.from_pretrained("vinai/bertweet-base", use_fast=False)
+
+>>> # 트랜스포머 버전 3.x 이상:
+>>> # tokenizer = AutoTokenizer.from_pretrained("vinai/bertweet-base")
+
+>>> # 입력된 트윗은 이미 정규화되었습니다!
+>>> line = "SC has first two presumptive cases of coronavirus , DHEC confirms HTTPURL via @USER :cry:"
+
+>>> input_ids = torch.tensor([tokenizer.encode(line)])
+
+>>> with torch.no_grad():
+... features = bertweet(input_ids) # Models outputs are now tuples
+
+>>> # With TensorFlow 2.0+:
+>>> # from transformers import TFAutoModel
+>>> # bertweet = TFAutoModel.from_pretrained("vinai/bertweet-base")
+```
+
+
+
+이 구현은 토큰화 방법을 제외하고는 BERT와 동일합니다. API 참조 정보는 [BERT 문서](bert) 를 참조하세요.
+
+
+
+## Bertweet 토큰화(BertweetTokenizer) [[transformers.BertweetTokenizer]]
+
+[[autodoc]] BertweetTokenizer
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/biogpt.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/biogpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..4b24af8493b9d5dc025416476cb75876c91e5249
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/biogpt.md
@@ -0,0 +1,109 @@
+
+
+# BioGPT [[biogpt]]
+
+## 개요 [[overview]]
+
+BioGPT는 Renqian Luo, Liai Sun, Yingce Xia, Tao Qin, Sheng Zhang, Hoifung Poon, Tie-Yan Liu에 의해 [BioGPT: generative pre-trained transformer for biomedical text generation and mining](https://academic.oup.com/bib/advance-article/doi/10.1093/bib/bbac409/6713511?guestAccessKey=a66d9b5d-4f83-4017-bb52-405815c907b9) 에서 제안된 모델입니다. BioGPT는 생물의학 텍스트 생성과 마이닝을 위해 도메인에 특화된 생성형 사전 학습 트랜스포머 언어 모델입니다. BioGPT는 트랜스포머 언어 모델 구조를 따르며, 1,500만 개의 PubMed 초록을 이용해 처음부터 학습되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*생물의학 분야에서 사전 학습된 언어 모델은 일반 자연어 처리 분야에서의 성공에 영감을 받아 점점 더 많은 주목을 받고 있습니다. 일반 언어 분야에서 사전 학습된 언어 모델의 두 가지 주요 계통인 BERT(및 그 변형)와 GPT(및 그 변형) 중 첫 번째는 생물의학 분야에서 BioBERT와 PubMedBERT와 같이 광범위하게 연구되었습니다. 이들은 다양한 분류 기반의 생물의학 작업에서 큰 성공을 거두었지만, 생성 능력의 부족은 그들의 적용 범위를 제한했습니다. 본 논문에서는 대규모 생물의학 문헌을 사전 학습한 도메인 특화 생성형 트랜스포머 언어 모델인 BioGPT를 제안합니다. 우리는 6개의 생물의학 자연어 처리 작업에서 BioGPT를 평가한 결과, 대부분의 작업에서 이전 모델보다 우수한 성능을 보였습니다. 특히, BC5CDR, KD-DTI, DDI 엔드-투-엔드 관계 추출 작업에서 각각 44.98%, 38.42%, 40.76%의 F1 점수를 기록하였으며, PubMedQA에서 78.2%의 정확도를 달성해 새로운 기록을 세웠습니다. 또한 텍스트 생성에 대한 사례 연구는 생물의학 용어에 대한 유창한 설명을 생성하는 데 있어 BioGPT의 장점을 더욱 입증했습니다.*
+
+이 모델은 [kamalkraj](https://huggingface.co/kamalkraj)에 의해 기여되었습니다. 원본 코드는 [여기](https://github.com/microsoft/BioGPT)에서 찾을 수 있습니다.
+
+## 사용 팁 [[usage-tips]]
+
+- BioGPT는 절대적 위치 임베딩(absolute position embedding)을 사용하므로, 입력을 왼쪽이 아닌 오른쪽에서 패딩하는 것이 권장됩니다.
+- BioGPT는 인과적 언어 모델링(Casual Langague Modeling, CLM) 목표로 학습되었기 때문에, 다음 토큰을 예측하는 데 강력한 성능을 보입니다. 이 기능을 활용하여 BioGPT는 구문적으로 일관된 텍스트를 생성할 수 있으며, 예시 스크립트 `run_generation.py`에서 이를 확인할 수 있습니다.
+- 이 모델은 `past_key_values`(PyTorch 용)를 입력으로 받을 수 있는데, 이는 이전에 계산된 키/값 어텐션 쌍입니다. 이 값을 사용하면 텍스트 생성 중 이미 계산된 값을 다시 계산하지 않도록 할 수 있습니다. PyTorch에서 `past_key_values` 인수는 BioGptForCausalLM.forward() 메소드에서 자세히 설명되어 있습니다.
+
+### Scaled Dot Product Attention(SDPA) 사용 [[using-scaled-dot-product-attention-sdpa]]
+
+PyTorch는 `torch.nn.functional`의 일부로 스케일된 점곱 어텐션(SDPA) 연산자를 기본적으로 포함합니다. 이 함수는 입력과 사용 중인 하드웨어에 따라 여러 구현을 적용할 수 있습니다. 자세한 내용은 [공식 문서](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html) 또는 [GPU 추론](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention) 페이지를 참조하세요.
+
+`torch>=2.1.1`에서 구현이 가능한 경우 SDPA는 기본적으로 사용되며, `attn_implementation="sdpa"`를 `from_pretrained()`에서 설정하여 SDPA 사용을 명시적으로 요청할 수 있습니다.
+
+```
+from transformers import BioGptForCausalLM
+model = BioGptForCausalLM.from_pretrained("microsoft/biogpt", attn_implementation="sdpa", torch_dtype=torch.float16)
+```
+
+NVIDIA GeForce RTX 2060-8GB, PyTorch 2.3.1, Ubuntu 20.04 환경에서 `float16` 및 CausalLM 헤드가 있는 `microsoft/biogpt` 모델로 로컬 벤치마크를 수행한 결과, 훈련 중 다음과 같은 속도 향상을 확인했습니다.
+
+최적의 속도 향상을 위해 모델을 반정밀도(예: `torch.float16` 또는 `torch.bfloat16`)로 로드하는 것이 좋습니다.
+
+| num_training_steps | batch_size | seq_len | is cuda | Time per batch (eager - s) | Time per batch (sdpa - s) | Speedup (%) | Eager peak mem (MB) | sdpa peak mem (MB) | Mem saving (%) |
+|--------------------|------------|---------|---------|----------------------------|---------------------------|-------------|---------------------|--------------------|----------------|
+| 100 | 1 | 128 | False | 0.038 | 0.031 | 21.301 | 1601.862 | 1601.497 | 0.023 |
+| 100 | 1 | 256 | False | 0.039 | 0.034 | 15.084 | 1624.944 | 1625.296 | -0.022 |
+| 100 | 2 | 128 | False | 0.039 | 0.033 | 16.820 | 1624.567 | 1625.296 | -0.045 |
+| 100 | 2 | 256 | False | 0.065 | 0.059 | 10.255 | 1672.164 | 1672.164 | 0.000 |
+| 100 | 4 | 128 | False | 0.062 | 0.058 | 6.998 | 1671.435 | 1672.164 | -0.044 |
+| 100 | 4 | 256 | False | 0.113 | 0.100 | 13.316 | 2350.179 | 1848.435 | 27.144 |
+| 100 | 8 | 128 | False | 0.107 | 0.098 | 9.883 | 2098.521 | 1848.435 | 13.530 |
+| 100 | 8 | 256 | False | 0.222 | 0.196 | 13.413 | 3989.980 | 2986.492 | 33.601 |
+
+NVIDIA GeForce RTX 2060-8GB, PyTorch 2.3.1, Ubuntu 20.04 환경에서 `float16` 및 AutoModel 헤드가 있는 `microsoft/biogpt` 모델로 추론 중 다음과 같은 속도 향상을 확인했습니다.
+
+| num_batches | batch_size | seq_len | is cuda | is half | use mask | Per token latency eager (ms) | Per token latency SDPA (ms) | Speedup (%) | Mem eager (MB) | Mem BT (MB) | Mem saved (%) |
+|-------------|------------|---------|---------|---------|----------|------------------------------|-----------------------------|-------------|----------------|--------------|---------------|
+| 50 | 1 | 64 | True | True | True | 0.115 | 0.098 | 17.392 | 716.998 | 716.998 | 0.000 |
+| 50 | 1 | 128 | True | True | True | 0.115 | 0.093 | 24.640 | 730.916 | 730.916 | 0.000 |
+| 50 | 2 | 64 | True | True | True | 0.114 | 0.096 | 19.204 | 730.900 | 730.900 | 0.000 |
+| 50 | 2 | 128 | True | True | True | 0.117 | 0.095 | 23.529 | 759.262 | 759.262 | 0.000 |
+| 50 | 4 | 64 | True | True | True | 0.113 | 0.096 | 18.325 | 759.229 | 759.229 | 0.000 |
+| 50 | 4 | 128 | True | True | True | 0.186 | 0.178 | 4.289 | 816.478 | 816.478 | 0.000 |
+
+
+## 리소스 [[resources]]
+
+- [인과적 언어 모델링 작업 가이드](../tasks/language_modeling)
+
+## BioGptConfig [[transformers.BioGptConfig]]
+
+[[autodoc]] BioGptConfig
+
+
+## BioGptTokenizer [[transformers.BioGptTokenizer]]
+
+[[autodoc]] BioGptTokenizer
+ - save_vocabulary
+
+
+## BioGptModel [[transformers.BioGptModel]]
+
+[[autodoc]] BioGptModel
+ - forward
+
+
+## BioGptForCausalLM [[transformers.BioGptForCausalLM]]
+
+[[autodoc]] BioGptForCausalLM
+ - forward
+
+
+## BioGptForTokenClassification [[transformers.BioGptForTokenClassification]]
+
+[[autodoc]] BioGptForTokenClassification
+ - forward
+
+
+## BioGptForSequenceClassification [[transformers.BioGptForSequenceClassification]]
+
+[[autodoc]] BioGptForSequenceClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/blip-2.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/blip-2.md
new file mode 100644
index 0000000000000000000000000000000000000000..ae3da11d3a18c310568f2b3360f5e8079c48a02c
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/blip-2.md
@@ -0,0 +1,98 @@
+
+
+# BLIP-2[[blip-2]]
+
+## 개요[[overview]]
+BLIP-2 모델은 Junnan Li, Dongxu Li, Silvio Savarese, Steven Hoi의 [BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arxiv.org/abs/2301.12597) 논문에서 제안되었습니다. BLIP-2는 동결된 사전 학습 이미지 인코더와 대규모 언어 모델(LLM)을 연결하는 12층의 경량 Transformer 인코더를 학습시켜, 여러 비전-언어 작업에서 SOTA(현재 최고의 성능)을 달성했습니다. 특히, BLIP-2는 800억 개의 파라미터를 가진 Flamingo 모델보다 제로샷 VQAv2에서 8.7% 더 높은 성능을 기록했으며, 학습 가능한 파라미터 수는 Flamingo보다 54배 적습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*비전-언어 사전 학습의 비용은 대규모 모델의 엔드-투-엔드 학습으로 인해 점점 더 부담스러워지고 있습니다. 본 논문은 사전 학습된 이미지 인코더와 대규모 언어 모델을 활용하여 비전-언어 사전 학습을 부트스트래핑하는 일반적이고 효율적인 사전 학습 전략인 BLIP-2를 제안합니다. BLIP-2는 경량화된 Querying Transformer를 통해 모달리티 간의 차이를 연결하며, 두 단계로 사전 학습됩니다. 첫 번째 단계는 동결된 이미지 인코더로부터 비전-언어 표현 학습을 부트스트래핑하고, 두 번째 단계는 동결된 언어 모델로부터 비전-언어 생성 학습을 부트스트래핑합니다. BLIP-2는 기존 방법들에 비해 훨씬 적은 학습 가능한 파라미터로 다양한 비전-언어 작업에서 최첨단 성능을 달성합니다. 예를 들어, 우리 모델은 제로샷 VQAv2에서 Flamingo80B보다 8.7% 높은 성능을 기록하며, 학습 가능한 파라미터 수는 54배 적습니다. 우리는 또한 자연어 명령을 따를 수 있는 제로샷 이미지-텍스트 생성의 새로운 기능을 입증했습니다.*
+
+
+
+ BLIP-2 구조. 원본 논문 에서 발췌.
+
+이 모델은 [nielsr](https://huggingface.co/nielsr)가 기여했습니다. 원본 코드는 [여기](https://github.com/salesforce/LAVIS/tree/5ee63d688ba4cebff63acee04adaef2dee9af207)에서 확인할 수 있습니다.
+
+## 사용 팁[[usage-tips]]
+
+- BLIP-2는 이미지와 조건에 따라 텍스트 프롬프트를 입력받아 조건부 텍스트를 생성합니다. 추론 시 [`generate`] 메소드를 사용하는 것이 권장됩니다.
+- [`Blip2Processor`]를 사용하여 모델에 이미지를 준비하고, 예측된 토큰 ID를 텍스트로 디코딩할 수 있습니다.
+
+## 자료[[resources]]
+
+BLIP-2를 시작하는 데 도움이 되는 공식 Hugging Face 및 커뮤니티(🌎 표시) 자료 목록입니다.
+
+- 이미지 캡셔닝, 시각 질문 응답(VQA), 채팅과 같은 대화형 작업을 위한 BLIP-2 데모 노트북은 [여기](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/BLIP-2)에서 찾을 수 있습니다.
+
+리소스를 제출하여 여기에 포함하고 싶다면 언제든지 풀 리퀘스트를 열어주세요! 리소스는 기존 리소스를 복제하지 않고 새로운 내용이어야 합니다.
+
+## Blip2Config[[transformers.Blip2Config]]
+
+[[autodoc]] Blip2Config
+ - from_vision_qformer_text_configs
+
+## Blip2VisionConfig[[transformers.Blip2VisionConfig]]
+
+[[autodoc]] Blip2VisionConfig
+
+## Blip2QFormerConfig[[transformers.Blip2QFormerConfig]]
+
+[[autodoc]] Blip2QFormerConfig
+
+## Blip2Processor[[transformers.Blip2Processor]]
+
+[[autodoc]] Blip2Processor
+
+## Blip2VisionModel[[transformers.Blip2VisionModel]]
+
+[[autodoc]] Blip2VisionModel
+ - forward
+
+## Blip2QFormerModel[[transformers.Blip2QFormerModel]]
+
+[[autodoc]] Blip2QFormerModel
+ - forward
+
+## Blip2Model[[transformers.Blip2Model]]
+
+[[autodoc]] Blip2Model
+ - forward
+ - get_text_features
+ - get_image_features
+ - get_qformer_features
+
+## Blip2ForConditionalGeneration[[transformers.Blip2ForConditionalGeneration]]
+
+[[autodoc]] Blip2ForConditionalGeneration
+ - forward
+ - generate
+
+## Blip2ForImageTextRetrieval[[transformers.Blip2ForImageTextRetrieval]]
+
+[[autodoc]] Blip2ForImageTextRetrieval
+ - forward
+
+## Blip2TextModelWithProjection[[transformers.Blip2TextModelWithProjection]]
+
+[[autodoc]] Blip2TextModelWithProjection
+
+## Blip2VisionModelWithProjection[[transformers.Blip2VisionModelWithProjection]]
+
+[[autodoc]] Blip2VisionModelWithProjection
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/blip.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/blip.md
new file mode 100644
index 0000000000000000000000000000000000000000..27e085315b891130598a49e4de909ccc28ecc8d5
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/blip.md
@@ -0,0 +1,136 @@
+
+
+# BLIP[[blip]]
+
+## 개요[[overview]]
+
+BLIP 모델은 Junnan Li, Dongxu Li, Caiming Xiong, Steven Hoi의 [BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation](https://arxiv.org/abs/2201.12086) 논문에서 제안되었습니다.
+
+BLIP은 여러 멀티모달 작업을 수행할 수 있는 모델입니다:
+
+- 시각 질문 응답 (Visual Question Answering, VQA)
+- 이미지-텍스트 검색 (이미지-텍스트 매칭)
+- 이미지 캡셔닝
+
+논문의 초록은 다음과 같습니다:
+
+*비전-언어 사전 학습(Vision-Language Pre-training, VLP)은 다양한 비전-언어 작업의 성능을 크게 향상시켰습니다. 하지만, 대부분의 기존 사전 학습 모델들은 이해 기반 작업이나 생성 기반 작업 중 하나에서만 뛰어난 성능을 발휘합니다. 또한 성능 향상은 주로 웹에서 수집한 노이즈가 많은 이미지-텍스트 쌍으로 데이터셋의 규모를 키우는 방식으로 이루어졌는데, 이는 최적의 지도 학습 방식이라고 보기 어렵습니다. 본 논문에서는 BLIP이라는 새로운 VLP 프레임워크를 제안합니다. 이 프레임워크는 비전-언어 이해 및 생성 작업 모두에 유연하게 적용될 수 있습니다. BLIP는 캡셔너가 합성 캡션을 생성하고 필터가 노이즈 캡션을 제거하는 부트스트래핑 방법을 통해 웹 데이터의 노이즈를 효과적으로 활용합니다. 우리는 이미지-텍스트 검색(Recall@1에서 +2.7%), 이미지 캡셔닝(CIDEr에서 +2.8%), 그리고 VQA(VQA 점수에서 +1.6%)와 같은 다양한 비전-언어 작업에서 최신 성과를 달성했습니다. 또한 BLIP은 제로샷 방식으로 비디오-언어 작업에 직접 전이될 때도 강력한 일반화 능력을 보여줍니다. 이 논문의 코드, 모델, 데이터셋은 공개되었습니다.*
+
+
+
+이 모델은 [ybelkada](https://huggingface.co/ybelkada)가 기여했습니다.
+원본 코드는 [여기](https://github.com/salesforce/BLIP)에서 찾을 수 있습니다.
+
+## 자료[[resources]]
+
+- [Jupyter notebook](https://github.com/huggingface/notebooks/blob/main/examples/image_captioning_blip.ipynb): 사용자 정의 데이터셋에서 BLIP를 이미지 캡셔닝으로 미세 조정하는 방법
+
+## BlipConfig[[transformers.BlipConfig]]
+
+[[autodoc]] BlipConfig
+ - from_text_vision_configs
+
+## BlipTextConfig[[transformers.BlipTextConfig]]
+
+[[autodoc]] BlipTextConfig
+
+## BlipVisionConfig[[transformers.BlipVisionConfig]]
+
+[[autodoc]] BlipVisionConfig
+
+## BlipProcessor[[transformers.BlipProcessor]]
+
+[[autodoc]] BlipProcessor
+
+## BlipImageProcessor[[transformers.BlipImageProcessor]]
+
+[[autodoc]] BlipImageProcessor
+ - preprocess
+
+
+
+
+## BlipModel[[transformers.BlipModel]]
+
+`BlipModel`은 향후 버전에서 더 이상 지원되지 않을 예정입니다. 목적에 따라 `BlipForConditionalGeneration`, `BlipForImageTextRetrieval` 또는 `BlipForQuestionAnswering`을 사용하십시오.
+
+[[autodoc]] BlipModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## BlipTextModel[[transformers.BlipTextModel]]
+
+[[autodoc]] BlipTextModel
+ - forward
+
+## BlipVisionModel[[transformers.BlipVisionModel]]
+
+[[autodoc]] BlipVisionModel
+ - forward
+
+## BlipForConditionalGeneration[[transformers.BlipForConditionalGeneration]]
+
+[[autodoc]] BlipForConditionalGeneration
+ - forward
+
+## BlipForImageTextRetrieval[[transformers.BlipForImageTextRetrieval]]
+
+[[autodoc]] BlipForImageTextRetrieval
+ - forward
+
+## BlipForQuestionAnswering[[transformers.BlipForQuestionAnswering]]
+
+[[autodoc]] BlipForQuestionAnswering
+ - forward
+
+
+
+
+## TFBlipModel[[transformers.TFBlipModel]]
+
+[[autodoc]] TFBlipModel
+ - call
+ - get_text_features
+ - get_image_features
+
+## TFBlipTextModel[[transformers.TFBlipTextModel]]
+
+[[autodoc]] TFBlipTextModel
+ - call
+
+## TFBlipVisionModel[[transformers.TFBlipVisionModel]]
+
+[[autodoc]] TFBlipVisionModel
+ - call
+
+## TFBlipForConditionalGeneration[[transformers.TFBlipForConditionalGeneration]]
+
+[[autodoc]] TFBlipForConditionalGeneration
+ - call
+
+## TFBlipForImageTextRetrieval[[transformers.TFBlipForImageTextRetrieval]]
+
+[[autodoc]] TFBlipForImageTextRetrieval
+ - call
+
+## TFBlipForQuestionAnswering[[transformers.TFBlipForQuestionAnswering]]
+
+[[autodoc]] TFBlipForQuestionAnswering
+ - call
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/chameleon.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/chameleon.md
new file mode 100644
index 0000000000000000000000000000000000000000..14a18a09765bd4cd737dcf40f0a8ffa82f173e3f
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/chameleon.md
@@ -0,0 +1,186 @@
+
+
+# Chameleon [[chameleon]]
+
+## 개요 [[overview]]
+
+Chameleon 모델은 META AI Chameleon 팀의 논문 [Chameleon: Mixed-Modal Early-Fusion Foundation Models](https://arxiv.org/abs/2405.09818v1)에서 제안되었습니다. Chameleon은 벡터 양자화를 사용하여 이미지를 토큰화함으로써 멀티모달 출력을 생성할 수 있는 비전-언어 모델입니다. 이 모델은 교차된 형식을 포함한 이미지와 텍스트를 입력으로 받으며, 텍스트 응답을 생성합니다. 이미지 생성 모듈은 아직 공개되지 않았습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*우리는 이미지와 텍스트를 임의의 순서로 이해하고 생성할 수 있는 early-fusion 토큰 기반의 혼합 모달(mixed-modal) 모델의 일종인 Chameleon을 소개합니다. 우리는 초기부터 안정적인 훈련 접근법, 정렬 방법, 그리고 early-fusion, 토큰 기반, 혼합 모달 설정에 맞춘 아키텍처 매개변수를 제시합니다. 이 모델들은 시각적 질문 응답, 이미지 캡션 생성, 텍스트 생성, 이미지 생성, 장문 혼합 모달 생성 등 포괄적인 작업 범위에서 평가되었습니다. Chameleon은 단일 모델에서 이미지 캡션 생성 작업에서의 최첨단 성능을 포함한 광범위하고 일반적으로 적용 가능한 능력을 보여주며, 텍스트 전용 작업에서 Llama-2를 능가하면서 Mixtral 8x7B와 Gemini-Pro와 같은 모델들 사이에서도 경쟁력을 갖추고 있습니다. 그리고 상당한 성능의 이미지 생성도 수행합니다. 또한 프롬프트나 출력에 이미지와 텍스트의 혼합 시퀀스가 포함된 새로운 장문 혼합 모달 생성 평가에서, 인간의 판단에 따르면 Gemini Pro와 GPT-4V를 포함한 훨씬 더 큰 모델의 성능과 동등하거나 이를 능가합니다. Chameleon은 완전한 멀티모달 문서의 통합 모델링에서 중요한 발전을 보여줍니다.*
+
+
+
+Chameleon은 이미지를 이산적인 토큰으로 변환하기 위해 벡터 양자화 모듈을 통합합니다. 이는 자기회귀 transformer를 사용한 이미지 생성을 가능하게 합니다. 원본 논문에서 가져왔습니다.
+
+이 모델은 [joaogante](https://huggingface.co/joaogante)와 [RaushanTurganbay](https://huggingface.co/RaushanTurganbay)가 기여했습니다. 원본 코드는 [여기](https://github.com/facebookresearch/chameleon)에서 찾을 수 있습니다.
+
+## 사용 팁 [[usage-tips]]
+
+- 더 정확한 결과를 위해, 배치 생성 시 `padding_side="left"`를 사용하는 것을 권장합니다. 생성하기 전에 `processor.tokenizer.padding_side = "left"`로 설정하십시오.
+
+- Chameleon은 안전성 정렬을 위해 튜닝되었음을 유의하십시오. 모델이 응답을 거부하는 경우, 열린 질문보다는 더 구체적으로 질문을 해보세요.
+
+- Chameleon은 채팅 형식으로 생성하므로, 생성된 텍스트는 항상 "assistant's turn"으로 표시됩니다. 프로세서를 호출할 때 `return_for_text_completion=True`를 전달하여 텍스트 완성 생성을 활성화할 수 있습니다.
+
+> [!NOTE]
+> Transformers에서의 Chameleon 구현은 이미지 임베딩을 병합할 위치를 나타내기 위해 특별한 이미지 토큰을 사용합니다. 특별한 이미지 토큰을 위해 새로운 토큰을 추가하지 않고 예약된 토큰 중 하나인 ``를 사용했습니다. 올바른 생성을 위해 프롬프트에서 이미지가 임베딩될 위치에 ``를 추가해야 합니다.
+
+## 사용 예제 [[usage-example]]
+
+### 단일 이미지 추론 [[single-image-inference]]
+
+Chameleon은 게이티드(gated) 모델이므로 Hugging Face Hub에 대한 액세스 권한이 있고 토큰으로 로그인했는지 확인하세요. 다음은 모델을 로드하고 반정밀도(`torch.bfloat16`)로 추론하는 방법입니다:
+
+```python
+from transformers import ChameleonProcessor, ChameleonForConditionalGeneration
+import torch
+from PIL import Image
+import requests
+
+processor = ChameleonProcessor.from_pretrained("facebook/chameleon-7b")
+model = ChameleonForConditionalGeneration.from_pretrained("facebook/chameleon-7b", torch_dtype=torch.bfloat16, device_map="cuda")
+
+# 이미지와 텍스트 프롬프트 준비
+url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+image = Image.open(requests.get(url, stream=True).raw)
+prompt = "이 이미지에서 무엇을 보나요?"
+
+inputs = processor(images=image, text=prompt, return_tensors="pt").to(model.device, dtype=torch.bfloat16)
+
+# 프롬프트를 자기회귀적으로 완성
+output = model.generate(**inputs, max_new_tokens=50)
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+### 다중 이미지 추론 [[multi-image-inference]]
+
+Chameleon은 여러 이미지를 입력으로 받아들이며, 이미지들은 동일한 프롬프트에 속하거나 다른 프롬프트에 속할 수 있습니다(배치 추론에서). 다음은 그 방법입니다:
+
+```python
+from transformers import ChameleonProcessor, ChameleonForConditionalGeneration
+import torch
+from PIL import Image
+import requests
+
+processor = ChameleonProcessor.from_pretrained("facebook/chameleon-7b")
+
+model = ChameleonForConditionalGeneration.from_pretrained("facebook/chameleon-7b", torch_dtype=torch.bfloat16, device_map="cuda")
+
+# 세 가지 다른 이미지 가져오기
+url = "https://www.ilankelman.org/stopsigns/australia.jpg"
+image_stop = Image.open(requests.get(url, stream=True).raw)
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image_cats = Image.open(requests.get(url, stream=True).raw)
+
+url = "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg"
+image_snowman = Image.open(requests.get(url, stream=True).raw)
+
+# 배치된 프롬프트 준비: 첫 번째는 다중 이미지 프롬프트이고 두 번째는 단일 이미지 프롬프트입니다
+prompts = [
+ "이 이미지들은 무엇이 공통점인가요?",
+ "이 이미지에 무엇이 나타나 있나요?"
+]
+
+# 이미지들을 텍스트 프롬프트에서 사용되어야 하는 순서대로 입력할 수 있습니다
+# 각 "" 토큰은 하나의 이미지를 사용하며, 다음 "" 토큰은 다음 이미지를 사용합니다
+inputs = processor(images=[image_stop, image_cats, image_snowman], text=prompts, padding=True, return_tensors="pt").to(device="cuda", dtype=torch.bfloat16)
+
+# 생성
+generate_ids = model.generate(**inputs, max_new_tokens=50)
+processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)
+```
+
+## 모델 최적화 [[model-optimization]]
+
+### Bitsandbytes를 사용한 양자화 [[quantization-using-bitsandbytes]]
+
+모델은 8비트 또는 4비트로 로드할 수 있으며, 이는 원본 모델의 성능을 유지하면서 메모리 요구 사항을 크게 줄여줍니다. 먼저 bitsandbytes를 설치하고(`pip install bitsandbytes`), 라이브러리가 지원하는 GPU/가속기를 사용 중인지 확인하십시오.
+
+
+
+bitsandbytes는 CUDA 이외의 여러 백엔드를 지원하도록 리팩터링되고 있습니다. 현재 ROCm(AMD GPU) 및 Intel CPU 구현이 성숙 단계이며, Intel XPU는 진행 중이고 Apple Silicon 지원은 Q4/Q1에 예상됩니다. 설치 지침 및 최신 백엔드 업데이트는 [이 링크](https://huggingface.co/docs/bitsandbytes/main/en/installation#multi-backend)를 방문하세요.
+
+전체 공개 전에 버그를 식별하는 데 도움이 되는 피드백을 환영합니다! 자세한 내용과 피드백은 [이 문서](https://huggingface.co/docs/bitsandbytes/main/en/non_cuda_backends)를 확인하세요.
+
+
+
+위의 코드 스니펫을 다음과 같이 변경하면 됩니다:
+
+```python
+from transformers import ChameleonForConditionalGeneration, BitsAndBytesConfig
+
+# 모델 양자화 방식 지정
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype=torch.bfloat16,
+)
+
+model = ChameleonForConditionalGeneration.from_pretrained("facebook/chameleon-7b", quantization_config=quantization_config, device_map="cuda")
+```
+
+### Flash-Attention 2와 SDPA를 사용하여 생성 속도 향상 [[use-flash-attention-2-and-sdpa-to-further-speed-up-generation]]
+
+이 모델은 최적화를 위해 Flash-Attention 2와 PyTorch의 [`torch.nn.functional.scaled_dot_product_attention`](https://pytorch.org/docs/master/generated/torch.nn.functional.scaled_dot_product_attention.html)를 모두 지원합니다. SDPA는 모델을 로드할 때 기본 옵션입니다. Flash Attention 2로 전환하려면 먼저 flash-attn을 설치해야 합니다. 해당 패키지 설치에 대해서는 [원본 리포지토리](https://github.com/Dao-AILab/flash-attention)를 참고하십시오. 위의 코드 스니펫을 다음과 같이 변경하면 됩니다:
+
+```python
+from transformers import ChameleonForConditionalGeneration
+
+model_id = "facebook/chameleon-7b"
+model = ChameleonForConditionalGeneration.from_pretrained(
+ model_id,
+ torch_dtype=torch.bfloat16,
+ low_cpu_mem_usage=True,
+ attn_implementation="flash_attention_2"
+).to(0)
+```
+
+## ChameleonConfig [[transformers.ChameleonConfig]]
+
+[[autodoc]] ChameleonConfig
+
+## ChameleonVQVAEConfig [[transformers.ChameleonVQVAEConfig]]
+
+[[autodoc]] ChameleonVQVAEConfig
+
+## ChameleonProcessor [[transformers.ChameleonProcessor]]
+
+[[autodoc]] ChameleonProcessor
+
+## ChameleonImageProcessor [[transformers.ChameleonImageProcessor]]
+
+[[autodoc]] ChameleonImageProcessor
+ - preprocess
+
+## ChameleonVQVAE [[transformers.ChameleonVQVAE]]
+
+[[autodoc]] ChameleonVQVAE
+ - forward
+
+## ChameleonModel [[transformers.ChameleonModel]]
+
+[[autodoc]] ChameleonModel
+ - forward
+
+## ChameleonForConditionalGeneration [[transformers.ChameleonForConditionalGeneration]]
+
+[[autodoc]] ChameleonForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/clip.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/clip.md
new file mode 100644
index 0000000000000000000000000000000000000000..5c19a31e10e658a694464cb079b513f5fccf62f6
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/clip.md
@@ -0,0 +1,318 @@
+
+
+# CLIP[[clip]]
+
+## 개요[[overview]]
+
+CLIP 모델은 Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh,
+Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever가 제안한 [자연어 지도(supervision)를 통한 전이 가능한 시각 모델 학습](https://arxiv.org/abs/2103.00020)라는 논문에서 소개되었습니다. CLIP(Contrastive Language-Image Pre-Training)은 다양한 이미지와 텍스트 쌍으로 훈련된 신경망 입니다. GPT-2와 3의 제로샷 능력과 유사하게, 해당 작업에 직접적으로 최적화하지 않고도 주어진 이미지에 대해 가장 관련성 있는 텍스트 스니펫을 예측하도록 자연어로 지시할 수 있습니다.
+
+해당 논문의 초록입니다.
+
+*최신 컴퓨터 비전 시스템은 미리 정해진 고정된 객체 카테고리 집합을 예측하도록 훈련됩니다. 이러한 제한된 형태의 지도는 다른 시각적 개념을 지정하기 위해 추가적인 라벨링된 데이터가 필요하므로 그 일반성과 사용성을 제한합니다. 이미지 원시 텍스트에서 직접 학습하는 것은 훨씬 더 광범위한 지도 소스를 활용하는 아주 좋은 대안입니다. 이미지와 캡션을 맞추는 간단한 사전 학습 작업이, 인터넷에서 수집한 4억 쌍의 이미지-텍스트 데이터셋에서 SOTA 수준의 이미지 표현을 처음부터 효율적이고 확장 가능하게 학습하는 방법임을 확인할 수 있습니다. 사전 훈련 후, 자연어는 학습된 시각적 개념을 참조하거나 새로운 개념을 설명하는 데 사용되어 모델의 하위 작업으로의 제로샷 전이를 가능하게 합니다. 해당 논문에서는 OCR, 비디오 내 행동 인식, 지리적 위치 파악, 그리고 많은 종류의 세밀한 객체 분류 등 30개 이상의 다양한 기존 컴퓨터 비전 데이터셋에 대한 벤치마킹을 통해 이 접근 방식의 성능을 연구합니다. 이 모델은 대부분의 작업에 대해 의미 있게 전이되며, 종종 데이터셋별 훈련 없이도 완전 지도 학습 기준선과 경쟁력 있는 성능을 보입니다. 예를 들어, ImageNet에서 원래 ResNet-50의 정확도를 제로샷으로 일치시키는데, 이는 ResNet-50이 훈련된 128만 개의 훈련 예제를 전혀 사용할 필요가 없었습니다. 코드 및 사전 훈련된 모델 가중치는 이 https URL에서 공개합니다.*
+
+이 모델은 [valhalla](https://huggingface.co/valhalla)에 의해 기여되었습니다.
+원본 코드는 [이곳](https://github.com/openai/CLIP)에서 확인할 수 있습니다.
+
+## 사용 팁과 예시[[usage-tips-and-example]]
+
+CLIP은 멀티모달 비전 밒 언어 모델입니다. 이미지-텍스트 유사도 계산과 제로샷 이미지 분류에 사용될 수 있습니다. CLIP은 ViT와 유사한 트랜스포머를 사용하여 시각적 특징을 추출하고, 인과적 언어 모델을 사용하여 텍스트 특징을 추출합니다. 그 후 텍스트와 시각적 특징 모두 동일한 차원의 잠재(latent) 공간으로 투영됩니다. 투영된 이미지와 텍스트 특징 사이의 내적이 유사도 점수로 사용됩니다.
+
+트랜스포머 인코더에 이미지를 입력하기 위해, 각 이미지는 고정 크기의 겹치지 않는 패치들의 시퀀스로 분할되고, 이후 선형 임베딩됩니다. [CLS]토큰이 전체 이미지의 표현으로 추가됩니다. 저자들은 또한 절대 위치 임베딩을 추가하고, 결과로 나온 벡터 시퀀스를 표준 트랜스포머 인토더에 입력합니다. [`CLIPImageProcessor`]는 모델을 위해 이미지를 리사이즈(또는 재스캐일링)하고 정규화하는데 사용될 수 있습니다.
+
+[`CLIPTokenizer`]는 텍스트를 인코딩하는데 사용됩니다. [`CLIPProcessor`]는 [`CLIPImageProcessor`]와 [`CLIPTokenizer`]를 하나의 인스턴스로 감싸서 텍스트를 인코딩하고 이미지를 준비하는데 모두 사용됩니다.
+
+다음 예시는 [`CLIPProcessor`]와 [`CLIPModel`]을 사용하여 이미지-텍스트 유사도 점수를 얻는 방법을 보여줍니다.
+
+
+```python
+>>> from PIL import Image
+>>> import requests
+
+>>> from transformers import CLIPProcessor, CLIPModel
+
+>>> model = CLIPModel.from_pretrained("openai/clip-vit-base-patch32")
+>>> processor = CLIPProcessor.from_pretrained("openai/clip-vit-base-patch32")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> inputs = processor(text=["a photo of a cat", "a photo of a dog"], images=image, return_tensors="pt", padding=True)
+
+>>> outputs = model(**inputs)
+>>> logits_per_image = outputs.logits_per_image # 이미지-텍스트 유사성 점수
+>>> probs = logits_per_image.softmax(dim=1) # 확률을 레이블링 하기위해서 소프트맥스를 취합니다.
+```
+
+
+### CLIP과 플래시 어텐션2 결합[[combining-clip-and-flash-attention-2]]
+
+먼저 최신버전의 플래시 어텐션2를 설치합니다.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+플래시 어텐션2와 호환되는 하드웨어를 가지고 있는지 확인하세요. 이에 대한 자세한 내용은 flash-attn 리포지토리의 공식문서에서 확인할 수 있습니다. 또한 모델을 반정밀도(`torch.float16`)로 로드하는 것을 잊지 마세요.
+
+
+
+작은 배치 크기를 사용할 때, 플래시 어텐션을 사용하면 모델이 느려지는 것을 느낄 수 있습니다.아래의 [플래시 어텐션과 SDPA를 사용한 예상 속도 향상](#Expected-speedups-with-Flash-Attention-and-SDPA) 섹션을 참조하여 적절한 어텐션 구현을 선택하세요.
+
+
+
+플래시 어텐션2를 사용해서 모델을 로드하고 구동하기 위해서 다음 스니펫을 참고하세요:
+
+```python
+>>> import torch
+>>> import requests
+>>> from PIL import Image
+
+>>> from transformers import CLIPProcessor, CLIPModel
+
+>>> device = "cuda"
+>>> torch_dtype = torch.float16
+
+>>> model = CLIPModel.from_pretrained(
+... "openai/clip-vit-base-patch32",
+... attn_implementation="flash_attention_2",
+... device_map=device,
+... torch_dtype=torch_dtype,
+... )
+>>> processor = CLIPProcessor.from_pretrained("openai/clip-vit-base-patch32")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> inputs = processor(text=["a photo of a cat", "a photo of a dog"], images=image, return_tensors="pt", padding=True)
+>>> inputs.to(device)
+
+>>> with torch.no_grad():
+... with torch.autocast(device):
+... outputs = model(**inputs)
+
+>>> logits_per_image = outputs.logits_per_image # 이미지-텍스트 유사성 점수
+>>> probs = logits_per_image.softmax(dim=1) # 확률을 레이블링 하기위해서 소프트맥스를 취합니다.
+>>> print(probs)
+tensor([[0.9946, 0.0052]], device='cuda:0', dtype=torch.float16)
+```
+
+
+### 스케일된 내적 어텐션 (Scaled dot-product Attention(SDPA)) 사용하기[[using-scaled-dot-product-attention-sdpa]]
+
+파이토치는 `torch.nn.functional`의 일부로 네이티브 스케일된 내적 어텐션(SPDA) 연산자를 포함하고 있습니다. 이 함수는 입력과 사용 중인 하드웨어에 따라 적용될 수 있는 여러 구현을 포함합니다. 자세한 정보는 [공식문서](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)나 [GPU 추론](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention) 페이지를 참조하세요.
+
+`torch>=2.1.1`에서는 구현이 가능할 때 SDPA가 기본적으로 사용되지만, `from_pretrained()` 함수에서 `attn_implementation="sdpa"`를 설정하여 SDPA를 명시적으로 사용하도록 요청할 수도 있습니다.
+
+```python
+from transformers import CLIPModel
+
+model = CLIPModel.from_pretrained("openai/clip-vit-base-patch32", torch_dtype=torch.float16, attn_implementation="sdpa")
+```
+
+최고의 속도향상을 위해서, 반정밀도로 모델을 로드하는 것을 추천합니다. (예를들면 `torch.float16` 또는 `torch.bfloat16`).
+
+### 플래시 어텐션과 스케일된 내적 어텐션(SDPA)으로 인해 예상되는 속도향상[[expected-speedups-with-flash-attention-and-sdpa]]
+
+로컬 벤치마크(NVIDIA A10G, PyTorch 2.3.1+cu121)에서 `float16`을 사용하여 `"openai/clip-vit-large-patch14"` 체크포인트로 추론을 수행했을 때, 다음과 같은 속도 향상을 확인 했습니다.
+[코드](https://gist.github.com/qubvel/ac691a54e54f9fae8144275f866a7ff8):
+
+#### CLIPTextModel[[cliptextmodel]]
+
+| Num text labels | Eager (s/iter) | FA2 (s/iter) | FA2 speedup | SDPA (s/iter) | SDPA speedup |
+|------------------:|-----------------:|---------------:|--------------:|----------------:|---------------:|
+| 4 | 0.009 | 0.012 | 0.737 | 0.007 | 1.269 |
+| 16 | 0.009 | 0.014 | 0.659 | 0.008 | 1.187 |
+| 32 | 0.018 | 0.021 | 0.862 | 0.016 | 1.142 |
+| 64 | 0.034 | 0.034 | 1.001 | 0.03 | 1.163 |
+| 128 | 0.063 | 0.058 | 1.09 | 0.054 | 1.174 |
+
+
+
+#### CLIPVisionModel[[clipvisionmodel]]
+
+| Image batch size | Eager (s/iter) | FA2 (s/iter) | FA2 speedup | SDPA (s/iter) | SDPA speedup |
+|-------------------:|-----------------:|---------------:|--------------:|----------------:|---------------:|
+| 1 | 0.016 | 0.013 | 1.247 | 0.012 | 1.318 |
+| 4 | 0.025 | 0.021 | 1.198 | 0.021 | 1.202 |
+| 16 | 0.093 | 0.075 | 1.234 | 0.075 | 1.24 |
+| 32 | 0.181 | 0.147 | 1.237 | 0.146 | 1.241 |
+
+
+
+#### CLIPModel[[clipmodel]]
+
+| Image batch size | Num text labels | Eager (s/iter) | FA2 (s/iter) | FA2 speedup | SDPA (s/iter) | SDPA speedup |
+|-------------------:|------------------:|-----------------:|---------------:|--------------:|----------------:|---------------:|
+| 1 | 4 | 0.025 | 0.026 | 0.954 | 0.02 | 1.217 |
+| 1 | 16 | 0.026 | 0.028 | 0.918 | 0.02 | 1.287 |
+| 1 | 64 | 0.042 | 0.046 | 0.906 | 0.036 | 1.167 |
+| 4 | 4 | 0.028 | 0.033 | 0.849 | 0.024 | 1.189 |
+| 4 | 16 | 0.034 | 0.035 | 0.955 | 0.029 | 1.169 |
+| 4 | 64 | 0.059 | 0.055 | 1.072 | 0.05 | 1.179 |
+| 16 | 4 | 0.096 | 0.088 | 1.091 | 0.078 | 1.234 |
+| 16 | 16 | 0.102 | 0.09 | 1.129 | 0.083 | 1.224 |
+| 16 | 64 | 0.127 | 0.11 | 1.157 | 0.105 | 1.218 |
+| 32 | 4 | 0.185 | 0.159 | 1.157 | 0.149 | 1.238 |
+| 32 | 16 | 0.19 | 0.162 | 1.177 | 0.154 | 1.233 |
+| 32 | 64 | 0.216 | 0.181 | 1.19 | 0.176 | 1.228 |
+
+## 자료[[resources]]
+
+CLIP을 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다.
+
+- [원격 센싱 (인공위성) 이미지와 캡션을 가지고 CLIP 미세조정하기](https://huggingface.co/blog/fine-tune-clip-rsicd):
+[RSICD dataset](https://github.com/201528014227051/RSICD_optimal)을 가지고 CLIP을 미세조정 하는 방법과 데이터 증강에 대한 성능 비교에 대한 블로그 포스트
+- 이 [예시 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/contrastive-image-text)는 [COCO dataset](https://cocodataset.org/#home)를 이용한 사전학습된 비전과 텍스트와 인코더를 사용해서 CLIP같은 비전-텍스트 듀얼 모델을 어떻게 학습시키는지 보여줍니다.
+
+
+
+- 사전학습된 CLIP모델을 이미지 캡셔닝을 위한 빔서치 추론에 어떻게 활용하는지에 관한 [노트북](https://colab.research.google.com/drive/1tuoAC5F4sC7qid56Z0ap-stR3rwdk0ZV?usp=sharing)
+
+**이미지 검색**
+
+- 사전학습된 CLIP모델과 MRR(Mean Reciprocal Rank) 점수 연산을 사용한 이미지 검색에 대한 [노트북](https://colab.research.google.com/drive/1bLVwVKpAndpEDHqjzxVPr_9nGrSbuOQd?usp=sharing). 🌎
+- 이미지 검색과 유사성 점수에 대해 보여주는 [노트북](https://colab.research.google.com/github/deep-diver/image_search_with_natural_language/blob/main/notebooks/Image_Search_CLIP.ipynb). 🌎
+- Multilingual CLIP를 사용해서 이미지와 텍스트를 어떻게 같은 벡터 공간에 매핑 시키는지에 대한 [노트북](https://colab.research.google.com/drive/1xO-wC_m_GNzgjIBQ4a4znvQkvDoZJvH4?usp=sharing). 🌎
+- [Unsplash](https://unsplash.com)와 [TMDB](https://www.themoviedb.org/) 데이터셋을 활용한 의미론적(semantic) 이미지 검색에서 CLIP을 구동하는 방법에 대한 [노트북](https://colab.research.google.com/github/vivien000/clip-demo/blob/master/clip.ipynb#scrollTo=uzdFhRGqiWkR). 🌎
+
+**설명 가능성**
+
+- 입력 토큰과 이미지 조각(segment) 사이의 유사성을 시각화 시키는 방법에 대한 [노트북](https://colab.research.google.com/github/hila-chefer/Transformer-MM-Explainability/blob/main/CLIP_explainability.ipynb). 🌎
+
+여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+## CLIPConfig[[transformers.CLIPConfig]]
+
+[[autodoc]] CLIPConfig
+ - from_text_vision_configs
+
+## CLIPTextConfig[[transformers.CLIPTextConfig]]
+
+[[autodoc]] CLIPTextConfig
+
+## CLIPVisionConfig[[transformers.CLIPVisionConfig]]
+
+[[autodoc]] CLIPVisionConfig
+
+## CLIPTokenizer[[transformers.CLIPTokenizer]]
+
+[[autodoc]] CLIPTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## CLIPTokenizerFast[[transformers.CLIPTokenizerFast]]
+
+[[autodoc]] CLIPTokenizerFast
+
+## CLIPImageProcessor[[transformers.CLIPImageProcessor]]
+
+[[autodoc]] CLIPImageProcessor
+ - preprocess
+
+## CLIPFeatureExtractor[[transformers.CLIPFeatureExtractor]]
+
+[[autodoc]] CLIPFeatureExtractor
+
+## CLIPProcessor[[transformers.CLIPProcessor]]
+
+[[autodoc]] CLIPProcessor
+
+
+
+
+## CLIPModel[[transformers.CLIPModel]]
+
+[[autodoc]] CLIPModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## CLIPTextModel[[transformers.CLIPTextModel]]
+
+[[autodoc]] CLIPTextModel
+ - forward
+
+## CLIPTextModelWithProjection[[transformers.CLIPTextModelWithProjection]]
+
+[[autodoc]] CLIPTextModelWithProjection
+ - forward
+
+## CLIPVisionModelWithProjection[[transformers.CLIPVisionModelWithProjection]]
+
+[[autodoc]] CLIPVisionModelWithProjection
+ - forward
+
+## CLIPVisionModel[[transformers.CLIPVisionModel]]
+
+[[autodoc]] CLIPVisionModel
+ - forward
+
+## CLIPForImageClassification[[transformers.CLIPForImageClassification]]
+
+[[autodoc]] CLIPForImageClassification
+ - forward
+
+
+
+
+## TFCLIPModel[[transformers.TFCLIPModel]]
+
+[[autodoc]] TFCLIPModel
+ - call
+ - get_text_features
+ - get_image_features
+
+## TFCLIPTextModel[[transformers.TFCLIPTextModel]]
+
+[[autodoc]] TFCLIPTextModel
+ - call
+
+## TFCLIPVisionModel[[transformers.TFCLIPVisionModel]]
+
+[[autodoc]] TFCLIPVisionModel
+ - call
+
+
+
+
+## FlaxCLIPModel[[transformers.FlaxCLIPModel]]
+
+[[autodoc]] FlaxCLIPModel
+ - __call__
+ - get_text_features
+ - get_image_features
+
+## FlaxCLIPTextModel[[transformers.FlaxCLIPTextModel]]
+
+[[autodoc]] FlaxCLIPTextModel
+ - __call__
+
+## FlaxCLIPTextModelWithProjection[[transformers.FlaxCLIPTextModelWithProjection]]
+
+[[autodoc]] FlaxCLIPTextModelWithProjection
+ - __call__
+
+## FlaxCLIPVisionModel[[transformers.FlaxCLIPVisionModel]]
+
+[[autodoc]] FlaxCLIPVisionModel
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/cohere.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/cohere.md
new file mode 100644
index 0000000000000000000000000000000000000000..c577764623f49672a27b78f850828cc21fa7a37b
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/cohere.md
@@ -0,0 +1,139 @@
+# Cohere[[cohere]]
+
+## 개요[[overview]]
+
+The Cohere Command-R 모델은 Cohere팀이 [Command-R: 프로덕션 규모의 검색 증강 생성](https://txt.cohere.com/command-r/)라는 블로그 포스트에서 소개 되었습니다.
+
+논문 초록:
+
+*Command-R은 기업의 프로덕션 규모 AI를 가능하게 하기 위해 RAG(검색 증강 생성)와 도구 사용을 목표로 하는 확장 가능한 생성 모델입니다. 오늘 우리는 대규모 프로덕션 워크로드를 목표로 하는 새로운 LLM인 Command-R을 소개합니다. Command-R은 높은 효율성과 강력한 정확성의 균형을 맞추는 '확장 가능한' 모델 카테고리를 대상으로 하여, 기업들이 개념 증명을 넘어 프로덕션 단계로 나아갈 수 있게 합니다.*
+
+*Command-R은 검색 증강 생성(RAG)이나 외부 API 및 도구 사용과 같은 긴 문맥 작업에 최적화된 생성 모델입니다. 이 모델은 RAG 애플리케이션을 위한 최고 수준의 통합을 제공하고 기업 사용 사례에서 뛰어난 성능을 발휘하기 위해 우리의 업계 선도적인 Embed 및 Rerank 모델과 조화롭게 작동하도록 설계되었습니다. 기업이 대규모로 구현할 수 있도록 만들어진 모델로서, Command-R은 다음과 같은 특징을 자랑합니다:
+- RAG 및 도구 사용에 대한 강력한 정확성
+- 낮은 지연 시간과 높은 처리량
+- 더 긴 128k 컨텍스트와 낮은 가격
+- 10개의 주요 언어에 걸친 강력한 기능
+- 연구 및 평가를 위해 HuggingFace에서 사용 가능한 모델 가중치
+
+모델 체크포인트는 [이곳](https://huggingface.co/CohereForAI/c4ai-command-r-v01)에서 확인하세요.
+이 모델은 [Saurabh Dash](https://huggingface.co/saurabhdash)과 [Ahmet Üstün](https://huggingface.co/ahmetustun)에 의해 기여 되었습니다. Hugging Face에서 이 코드의 구현은 [GPT-NeoX](https://github.com/EleutherAI/gpt-neox)에 기반하였습니다.
+
+## 사용 팁[[usage-tips]]
+
+
+
+Hub에 업로드된 체크포인트들은 `torch_dtype = 'float16'`을 사용합니다.
+이는 `AutoModel` API가 체크포인트를 `torch.float32`에서 `torch.float16`으로 변환하는 데 사용됩니다.
+
+온라인 가중치의 `dtype`은 `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`를 사용하여 모델을 초기화할 때 `torch_dtype="auto"`를 사용하지 않는 한 대부분 무관합니다. 그 이유는 모델이 먼저 다운로드되고(온라인 체크포인트의 `dtype` 사용), 그 다음 `torch`의 기본 `dtype`으로 변환되며(이때 `torch.float32`가 됨), 마지막으로 config에 `torch_dtype`이 제공된 경우 이를 사용하기 때문입니다.
+
+모델을 `float16`으로 훈련하는 것은 권장되지 않으며 `nan`을 생성하는 것으로 알려져 있습니다. 따라서 모델은 `bfloat16`으로 훈련해야 합니다.
+
+모델과 토크나이저는 다음과 같이 로드할 수 있습니다:
+
+```python
+# pip install transformers
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+model_id = "CohereForAI/c4ai-command-r-v01"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id)
+
+# Format message with the command-r chat template
+messages = [{"role": "user", "content": "Hello, how are you?"}]
+input_ids = tokenizer.apply_chat_template(messages, tokenize=True, add_generation_prompt=True, return_tensors="pt")
+## <|START_OF_TURN_TOKEN|><|USER_TOKEN|>Hello, how are you?<|END_OF_TURN_TOKEN|><|START_OF_TURN_TOKEN|><|CHATBOT_TOKEN|>
+
+gen_tokens = model.generate(
+ input_ids,
+ max_new_tokens=100,
+ do_sample=True,
+ temperature=0.3,
+ )
+
+gen_text = tokenizer.decode(gen_tokens[0])
+print(gen_text)
+```
+
+- Flash Attention 2를 `attn_implementation="flash_attention_2"`를 통해 사용할 때는, `from_pretrained` 클래스 메서드에 `torch_dtype`을 전달하지 말고 자동 혼합 정밀도 훈련(Automatic Mixed-Precision training)을 사용하세요. `Trainer`를 사용할 때는 단순히 `fp16` 또는 `bf16`을 `True`로 지정하면 됩니다. 그렇지 않은 경우에는 `torch.autocast`를 사용하고 있는지 확인하세요. 이는 Flash Attention이 `fp16`와 `bf16` 데이터 타입만 지원하기 때문에 필요합니다.
+
+## 리소스[[resources]]
+
+Command-R을 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+
+
+
+FP16 모델 로딩
+```python
+# pip install transformers
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+model_id = "CohereForAI/c4ai-command-r-v01"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id)
+
+# command-r 챗 템플릿으로 메세지 형식을 정하세요
+messages = [{"role": "user", "content": "Hello, how are you?"}]
+input_ids = tokenizer.apply_chat_template(messages, tokenize=True, add_generation_prompt=True, return_tensors="pt")
+## <|START_OF_TURN_TOKEN|><|USER_TOKEN|>Hello, how are you?<|END_OF_TURN_TOKEN|><|START_OF_TURN_TOKEN|><|CHATBOT_TOKEN|>
+
+gen_tokens = model.generate(
+ input_ids,
+ max_new_tokens=100,
+ do_sample=True,
+ temperature=0.3,
+ )
+
+gen_text = tokenizer.decode(gen_tokens[0])
+print(gen_text)
+```
+
+bitsandbytes 라이브러리를 이용해서 4bit 양자화된 모델 로딩
+```python
+# pip install transformers bitsandbytes accelerate
+from transformers import AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig
+
+bnb_config = BitsAndBytesConfig(load_in_4bit=True)
+
+model_id = "CohereForAI/c4ai-command-r-v01"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=bnb_config)
+
+gen_tokens = model.generate(
+ input_ids,
+ max_new_tokens=100,
+ do_sample=True,
+ temperature=0.3,
+ )
+
+gen_text = tokenizer.decode(gen_tokens[0])
+print(gen_text)
+```
+
+
+## CohereConfig[[transformers.CohereConfig]]
+
+[[autodoc]] CohereConfig
+
+## CohereTokenizerFast[[transformers.CohereTokenizerFast]]
+
+[[autodoc]] CohereTokenizerFast
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - update_post_processor
+ - save_vocabulary
+
+## CohereModel[[transformers.CohereModel]]
+
+[[autodoc]] CohereModel
+ - forward
+
+
+## CohereForCausalLM[[transformers.CohereForCausalLM]]
+
+[[autodoc]] CohereForCausalLM
+ - forward
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/convbert.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/convbert.md
new file mode 100644
index 0000000000000000000000000000000000000000..ec64a369b56a3f0e33f9e41c44f6b95555dc36dd
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/convbert.md
@@ -0,0 +1,135 @@
+
+
+# ConvBERT [[convbert]]
+
+
+
+## 개요 [[overview]]
+
+ConvBERT 모델은 Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan에 의해 제안되었으며, 제안 논문 제목은 [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496)입니다.
+
+논문의 초록은 다음과 같습니다:
+
+*BERT와 그 변형 모델과 같은 사전 학습된 언어 모델들은 최근 다양한 자연어 이해 과제에서 놀라운 성과를 이루었습니다. 그러나 BERT는 글로벌 셀프 어텐션 블록에 크게 의존하기 때문에 메모리 사용량이 많고 계산 비용이 큽니다. 모든 어텐션 헤드가 글로벌 관점에서 어텐션 맵을 생성하기 위해 입력 시퀀스 전체를 탐색하지만, 일부 헤드는 로컬 종속성만 학습할 필요가 있다는 것을 발견했습니다. 이는 불필요한 계산이 포함되어 있음을 의미합니다. 따라서 우리는 이러한 self-attention 헤드들을 대체하여 로컬 종속성을 직접 모델링하기 위해 새로운 span 기반 동적 컨볼루션을 제안합니다. 새로운 컨볼루션 헤드와 나머지 self-attention 헤드들이 결합하여 글로벌 및 로컬 문맥 학습에 더 효율적인 혼합 어텐션 블록을 구성합니다. 우리는 BERT에 이 혼합 어텐션 설계를 적용하여 ConvBERT 모델을 구축했습니다. 실험 결과, ConvBERT는 다양한 다운스트림 과제에서 BERT 및 그 변형 모델보다 더 우수한 성능을 보였으며, 훈련 비용과 모델 파라미터 수가 더 적었습니다. 특히 ConvBERTbase 모델은 GLUE 스코어 86.4를 달성하여 ELECTRAbase보다 0.7 높은 성과를 보이며, 훈련 비용은 1/4 이하로 줄었습니다. 코드와 사전 학습된 모델은 공개될 예정입니다.*
+
+이 모델은 [abhishek](https://huggingface.co/abhishek)에 의해 기여되었으며, 원본 구현은 여기에서 찾을 수 있습니다 : https://github.com/yitu-opensource/ConvBert
+
+
+
+## 사용 팁 [[usage-tips]]
+ConvBERT 훈련 팁은 BERT와 유사합니다. 사용 팁은 [BERT 문서](bert).를 참고하십시오.
+
+
+## 리소스 [[resources]]
+
+- [텍스트 분류 작업 가이드 (Text classification task guide)](../tasks/sequence_classification)
+- [토큰 분류 작업 가이드 (Token classification task guide)](../tasks/token_classification)
+- [질의응답 작업 가이드 (Question answering task guide)](../tasks/question_answering)
+- [마스킹된 언어 모델링 작업 가이드 (Masked language modeling task guide)](../tasks/masked_language_modeling)
+- [다중 선택 작업 가이드 (Multiple choice task guide)](../tasks/multiple_choice)
+
+## ConvBertConfig [[transformers.ConvBertConfig]]
+
+[[autodoc]] ConvBertConfig
+
+## ConvBertTokenizer [[transformers.ConvBertTokenizer]]
+
+[[autodoc]] ConvBertTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## ConvBertTokenizerFast [[transformers.ConvBertTokenizerFast]]
+
+[[autodoc]] ConvBertTokenizerFast
+
+
+
+
+## ConvBertModel [[transformers.ConvBertModel]]
+
+[[autodoc]] ConvBertModel
+ - forward
+
+## ConvBertForMaskedLM [[transformers.ConvBertForMaskedLM]]
+
+[[autodoc]] ConvBertForMaskedLM
+ - forward
+
+## ConvBertForSequenceClassification [[transformers.ConvBertForSequenceClassification]]
+
+[[autodoc]] ConvBertForSequenceClassification
+ - forward
+
+## ConvBertForMultipleChoice [[transformers.ConvBertForMultipleChoice]]
+
+[[autodoc]] ConvBertForMultipleChoice
+ - forward
+
+## ConvBertForTokenClassification [[transformers.ConvBertForTokenClassification]]
+
+[[autodoc]] ConvBertForTokenClassification
+ - forward
+
+## ConvBertForQuestionAnswering [[transformers.ConvBertForQuestionAnswering]]
+
+[[autodoc]] ConvBertForQuestionAnswering
+ - forward
+
+
+
+
+## TFConvBertModel [[transformers.TFConvBertModel]]
+
+[[autodoc]] TFConvBertModel
+ - call
+
+## TFConvBertForMaskedLM [[transformers.TFConvBertForMaskedLM]]
+
+[[autodoc]] TFConvBertForMaskedLM
+ - call
+
+## TFConvBertForSequenceClassification [[transformers.TFConvBertForSequenceClassification]]
+
+[[autodoc]] TFConvBertForSequenceClassification
+ - call
+
+## TFConvBertForMultipleChoice [[transformers.TFConvBertForMultipleChoice]]
+
+[[autodoc]] TFConvBertForMultipleChoice
+ - call
+
+## TFConvBertForTokenClassification [[transformers.TFConvBertForTokenClassification]]
+
+[[autodoc]] TFConvBertForTokenClassification
+ - call
+
+## TFConvBertForQuestionAnswering [[transformers.TFConvBertForQuestionAnswering]]
+
+[[autodoc]] TFConvBertForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/dbrx.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/dbrx.md
new file mode 100644
index 0000000000000000000000000000000000000000..4b33e95700691edd07f82c989c9c07e36aa0b419
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/dbrx.md
@@ -0,0 +1,125 @@
+
+
+# DBRX[[dbrx]]
+
+## 개요[[overview]]
+
+DBRX는 [트랜스포머 기반의](https://www.isattentionallyouneed.com/) 다음 토큰을 예측하는 디코더 전용 LLM 모델입니다.
+총 132B 매개변수를 가진 *세밀한* 전문가 혼합(MoE) 아키텍처를 사용하며, 이 중 36B 매개변수가 입력마다 활성화됩니다.
+12T 토큰의 텍스트와 코드 데이터로 사전 학습되었습니다.
+
+Mixtral-8x7B와 Grok-1과 같은 다른 공개 MoE 모델들과 비교했을 때, DBRX는 더 많은 수의 작은 전문가들을 사용하는 세밀한 구조를 가지고 있습니다. DBRX는 16개의 전문가 중 4개를 선택하는 반면, Mixtral-8x7B와 Grok-1은 8개의 전문가 중 2개를 선택합니다.
+
+이는 65배 더 많은 전문가 조합을 가능하게 하며, 이를 통해 모델의 품질이 향상되는 것을 발견했습니다.
+DBRX는 회전 위치 인코딩(RoPE), 게이트 선형 유닛(GLU), 그룹 쿼리 어텐션(GQA)을 사용합니다.
+BPE 기반 모델이며 [tiktoken](https://github.com/openai/tiktoken) 저장소에 설명된 GPT-4 토크나이저를 사용합니다.
+이러한 선택들은 철저한 평가와 스케일링 실험을 기반으로 이루어졌습니다.
+
+DBRX는 신중하게 선별된 12T 토큰의 데이터로 사전 학습되었으며, 최대 문맥 길이는 32K 토큰입니다.
+이 데이터는 토큰 대비 MPT 계열 모델 학습에 사용된 데이터보다 최소 2배 이상 더 좋은 것으로 추정됩니다.
+이 새로운 데이터셋은 데이터 처리를 위한 Apache Spark™와 Databricks 노트북, 그리고 데이터 관리와 거버넌스를 위한 Unity Catalog를 포함한 Databricks 도구 전체를 활용하여 개발되었습니다.
+우리는 사전 학습을 위해 커리큘럼 학습을 사용했으며, 학습 중 데이터 믹스를 변경하는 방식이 모델 품질을 상당히 개선한다는 것을 발견했습니다.
+
+
+DBRX Instruct와 DBRX Base에 대한 더 자세한 정보는 이 [기술 블로그 포스트](https://www.databricks.com/blog/introducing-dbrx-new-state-art-open-llm)에서 확인할 수 있습니다.
+
+이 모델은 [eitan-turok](https://huggingface.co/eitanturok)와 [abhi-db](https://huggingface.co/abhi-db)가 기여했습니다. 원본 코드는 [이곳](https://github.com/databricks/dbrx-instruct)에서 찾을 수 있지만, 최신 버전이 아닐 수 있습니다.
+
+## 사용 예[[usage-examples]]
+
+`generate()` 메소드는 DBRX를 사용하여 텍스트를 생성하는 데 사용될 수 있습니다. 표준 어텐션 구현, 플래시 어텐션, PyTorch의 스케일된 내적 어텐션(Scaled Dot-Product Attention)을 사용하여 생성할 수 있습니다. 후자의 두 어텐션 구현 방식은 처리 속도를 크게 높여줍니다.
+
+```python
+from transformers import DbrxForCausalLM, AutoTokenizer
+import torch
+
+tokenizer = AutoTokenizer.from_pretrained("databricks/dbrx-instruct", token="YOUR_HF_TOKEN")
+model = DbrxForCausalLM.from_pretrained(
+ "databricks/dbrx-instruct",
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+ token="YOUR_HF_TOKEN",
+ )
+
+input_text = "What does it take to build a great LLM?"
+messages = [{"role": "user", "content": input_text}]
+input_ids = tokenizer.apply_chat_template(messages, return_dict=True, tokenize=True, add_generation_prompt=True, return_tensors="pt").to("cuda")
+
+outputs = model.generate(**input_ids, max_new_tokens=200)
+print(tokenizer.decode(outputs[0]))
+```
+
+`pip install flash-attn`를 통해 플래시 어텐션을 설치하면, 더 빠른 생성이 가능합니다. (플래시 어텐션에 대한 HuggingFace 문서는 [이곳](https://huggingface.co/docs/transformers/perf_infer_gpu_one#flashattention-2)에서 확인할 수 있습니다.)
+
+
+```python
+from transformers import DbrxForCausalLM, AutoTokenizer
+import torch
+
+tokenizer = AutoTokenizer.from_pretrained("databricks/dbrx-instruct", token="YOUR_HF_TOKEN")
+model = DbrxForCausalLM.from_pretrained(
+ "databricks/dbrx-instruct",
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+ token="YOUR_HF_TOKEN",
+ attn_implementation="flash_attention_2",
+ )
+
+input_text = "What does it take to build a great LLM?"
+messages = [{"role": "user", "content": input_text}]
+input_ids = tokenizer.apply_chat_template(messages, return_dict=True, tokenize=True, add_generation_prompt=True, return_tensors="pt").to("cuda")
+
+outputs = model.generate(**input_ids, max_new_tokens=200)
+print(tokenizer.decode(outputs[0]))
+```
+
+PyTorch의 스케일된 내적 어텐션을 사용하여도 더 빠른 생성이 가능합니다. (스케일된 내적 어텐션에 대한 HuggingFace 문서는 [이곳](https://huggingface.co/docs/transformers/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)에서 확인할 수 있습니다.)
+
+
+```python
+from transformers import DbrxForCausalLM, AutoTokenizer
+import torch
+
+tokenizer = AutoTokenizer.from_pretrained("databricks/dbrx-instruct", token="YOUR_HF_TOKEN")
+model = DbrxForCausalLM.from_pretrained(
+ "databricks/dbrx-instruct",
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+ token="YOUR_HF_TOKEN",
+ attn_implementation="sdpa",
+ )
+
+input_text = "What does it take to build a great LLM?"
+messages = [{"role": "user", "content": input_text}]
+input_ids = tokenizer.apply_chat_template(messages, return_dict=True, tokenize=True, add_generation_prompt=True, return_tensors="pt").to("cuda")
+
+outputs = model.generate(**input_ids, max_new_tokens=200)
+print(tokenizer.decode(outputs[0]))
+```
+
+## DbrxConfig[[transformers.DbrxConfig]]
+
+[[autodoc]] DbrxConfig
+
+
+## DbrxModel[[transformers.DbrxModel]]
+
+[[autodoc]] DbrxModel
+ - forward
+
+
+## DbrxForCausalLM[[transformers.DbrxForCausalLM]]
+
+[[autodoc]] DbrxForCausalLM
+ - forward
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/deberta-v2.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/deberta-v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..2e590ad8a5abcf90da995dc90b6592c8a205b309
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/deberta-v2.md
@@ -0,0 +1,147 @@
+
+
+# DeBERTa-v2
+
+## 개요
+
+
+DeBERTa 모델은 Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen이 작성한 [DeBERTa: 분리된 어텐션을 활용한 디코딩 강화 BERT](https://arxiv.org/abs/2006.03654)이라는 논문에서 제안되었습니다. 이 모델은 2018년 Google이 발표한 BERT 모델과 2019년 Facebook이 발표한 RoBERTa 모델을 기반으로 합니다.
+DeBERTa는 RoBERTa에서 사용된 데이터의 절반만을 사용하여 분리된(disentangled) 어텐션과 향상된 마스크 디코더 학습을 통해 RoBERTa를 개선했습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*사전 학습된 신경망 언어 모델의 최근 발전은 많은 자연어 처리(NLP) 작업의 성능을 크게 향상시켰습니다. 본 논문에서는 두 가지 새로운 기술을 사용하여 BERT와 RoBERTa 모델을 개선한 새로운 모델 구조인 DeBERTa를 제안합니다. 첫 번째는 분리된 어텐션 메커니즘으로, 각 단어가 내용과 위치를 각각 인코딩하는 두 개의 벡터로 표현되며, 단어들 간의 어텐션 가중치는 내용과 상대적 위치에 대한 분리된 행렬을 사용하여 계산됩니다. 두 번째로, 모델 사전 학습을 위해 마스킹된 토큰을 예측하는 출력 소프트맥스 층을 대체하는 향상된 마스크 디코더가 사용됩니다. 우리는 이 두 가지 기술이 모델 사전 학습의 효율성과 다운스트림 작업의 성능을 크게 향상시킨다는 것을 보여줍니다. RoBERTa-Large와 비교했을 때, 절반의 학습 데이터로 학습된 DeBERTa 모델은 광범위한 NLP 작업에서 일관되게 더 나은 성능을 보여주며, MNLI에서 +0.9%(90.2% vs 91.1%), SQuAD v2.0에서 +2.3%(88.4% vs 90.7%), RACE에서 +3.6%(83.2% vs 86.8%)의 성능 향상을 달성했습니다. DeBERTa 코드와 사전 학습된 모델은 https://github.com/microsoft/DeBERTa 에서 공개될 예정입니다.*
+
+
+다음 정보들은 [원본 구현 저장소](https://github.com/microsoft/DeBERTa)에서 보실 수 있습니다. DeBERTa v2는 DeBERTa의 두번째 모델입니다.
+DeBERTa v2는 SuperGLUE 단일 모델 제출에 사용된 1.5B 모델을 포함하며, 인간 기준점(베이스라인) 89.8점 대비 89.9점을 달성했습니다. 저자의
+[블로그](https://www.microsoft.com/en-us/research/blog/microsoft-deberta-surpasses-human-performance-on-the-superglue-benchmark/)에서 더 자세한 정보를 확인할 수 있습니다.
+
+v2의 새로운 점:
+
+- **어휘(Vocabulary)** v2에서는 학습 데이터로부터 구축된 128K 크기의 새로운 어휘를 사용하도록 토크나이저가 변경되었습니다. GPT2 기반 토크나이저 대신, 이제는 [센텐스피스 기반](https://github.com/google/sentencepiece) 토크나이저를 사용합니다.
+- **nGiE[n그램 유도(Induced) 입력 인코딩]** DeBERTa-v2 모델은 입력 토큰들의 지역적 의존성을 더 잘 학습하기 위해 첫 번째 트랜스포머 층과 함께 추가적인 합성곱 층을 사용합니다.
+- **어텐션 층에서 위치 투영 행렬과 내용 투영 행렬 공유** 이전 실험들을 기반으로, 이는 성능에 영향을 주지 않으면서 매개변수를 절약할 수 있습니다.
+- **상대적 위치를 인코딩하기 위한 버킷 적용** DeBERTa-v2 모델은 T5와 유사하게 상대적 위치를 인코딩하기 위해 로그 버킷을 사용합니다.
+- **900M 모델 & 1.5B 모델** 900M과 1.5B, 두 가지 추가 모델 크기가 제공되며, 이는 다운스트림 작업의 성능을 크게 향상시킵니다.
+
+[DeBERTa](https://huggingface.co/DeBERTa) 모델의 텐서플로 2.0 구현은 [kamalkraj](https://huggingface.co/kamalkraj)가 기여했습니다. 원본 코드는 [이곳](https://github.com/microsoft/DeBERTa)에서 확인하실 수 있습니다.
+
+## 자료
+
+- [텍스트 분류 작업 가이드](../tasks/sequence_classification)
+- [토큰 분류 작업 가이드](../tasks/token_classification)
+- [질의응답 작업 가이드](../tasks/question_answering)
+- [마스크 언어 모델링 작업 가이드](../tasks/masked_language_modeling)
+- [다중 선택 작업 가이드](../tasks/multiple_choice)
+
+## DebertaV2Config
+
+[[autodoc]] DebertaV2Config
+
+## DebertaV2Tokenizer
+
+[[autodoc]] DebertaV2Tokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## DebertaV2TokenizerFast
+
+[[autodoc]] DebertaV2TokenizerFast
+ - build_inputs_with_special_tokens
+ - create_token_type_ids_from_sequences
+
+
+
+
+## DebertaV2Model
+
+[[autodoc]] DebertaV2Model
+ - forward
+
+## DebertaV2PreTrainedModel
+
+[[autodoc]] DebertaV2PreTrainedModel
+ - forward
+
+## DebertaV2ForMaskedLM
+
+[[autodoc]] DebertaV2ForMaskedLM
+ - forward
+
+## DebertaV2ForSequenceClassification
+
+[[autodoc]] DebertaV2ForSequenceClassification
+ - forward
+
+## DebertaV2ForTokenClassification
+
+[[autodoc]] DebertaV2ForTokenClassification
+ - forward
+
+## DebertaV2ForQuestionAnswering
+
+[[autodoc]] DebertaV2ForQuestionAnswering
+ - forward
+
+## DebertaV2ForMultipleChoice
+
+[[autodoc]] DebertaV2ForMultipleChoice
+ - forward
+
+
+
+
+## TFDebertaV2Model
+
+[[autodoc]] TFDebertaV2Model
+ - call
+
+## TFDebertaV2PreTrainedModel
+
+[[autodoc]] TFDebertaV2PreTrainedModel
+ - call
+
+## TFDebertaV2ForMaskedLM
+
+[[autodoc]] TFDebertaV2ForMaskedLM
+ - call
+
+## TFDebertaV2ForSequenceClassification
+
+[[autodoc]] TFDebertaV2ForSequenceClassification
+ - call
+
+## TFDebertaV2ForTokenClassification
+
+[[autodoc]] TFDebertaV2ForTokenClassification
+ - call
+
+## TFDebertaV2ForQuestionAnswering
+
+[[autodoc]] TFDebertaV2ForQuestionAnswering
+ - call
+
+## TFDebertaV2ForMultipleChoice
+
+[[autodoc]] TFDebertaV2ForMultipleChoice
+ - call
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/deberta.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/deberta.md
new file mode 100644
index 0000000000000000000000000000000000000000..6f82bed033a0e063b80210a71325741868fdc994
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/deberta.md
@@ -0,0 +1,152 @@
+
+
+# DeBERTa[[deberta]]
+
+## 개요[[overview]]
+
+
+DeBERTa 모델은 Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen이 작성한 [DeBERTa: 분리된 어텐션을 활용한 디코딩 강화 BERT](https://arxiv.org/abs/2006.03654)이라는 논문에서 제안되었습니다. 이 모델은 2018년 Google이 발표한 BERT 모델과 2019년 Facebook이 발표한 RoBERTa 모델을 기반으로 합니다.
+DeBERTa는 RoBERTa에서 사용된 데이터의 절반만을 사용하여 분리된(disentangled) 어텐션과 향상된 마스크 디코더 학습을 통해 RoBERTa를 개선했습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*사전 학습된 신경망 언어 모델의 최근 발전은 많은 자연어 처리(NLP) 작업의 성능을 크게 향상시켰습니다. 본 논문에서는 두 가지 새로운 기술을 사용하여 BERT와 RoBERTa 모델을 개선한 새로운 모델 구조인 DeBERTa를 제안합니다. 첫 번째는 분리된 어텐션 메커니즘으로, 각 단어가 내용과 위치를 각각 인코딩하는 두 개의 벡터로 표현되며, 단어들 간의 어텐션 가중치는 내용과 상대적 위치에 대한 분리된 행렬을 사용하여 계산됩니다. 두 번째로, 모델 사전 학습을 위해 마스킹된 토큰을 예측하는 출력 소프트맥스 층을 대체하는 향상된 마스크 디코더가 사용됩니다. 우리는 이 두 가지 기술이 모델 사전 학습의 효율성과 다운스트림 작업의 성능을 크게 향상시킨다는 것을 보여줍니다. RoBERTa-Large와 비교했을 때, 절반의 학습 데이터로 학습된 DeBERTa 모델은 광범위한 NLP 작업에서 일관되게 더 나은 성능을 보여주며, MNLI에서 +0.9%(90.2% vs 91.1%), SQuAD v2.0에서 +2.3%(88.4% vs 90.7%), RACE에서 +3.6%(83.2% vs 86.8%)의 성능 향상을 달성했습니다. DeBERTa 코드와 사전 학습된 모델은 https://github.com/microsoft/DeBERTa 에서 공개될 예정입니다.*
+
+[DeBERTa](https://huggingface.co/DeBERTa) 모델의 텐서플로 2.0 구현은 [kamalkraj](https://huggingface.co/kamalkraj)가 기여했습니다. 원본 코드는 [이곳](https://github.com/microsoft/DeBERTa)에서 확인하실 수 있습니다.
+
+## 리소스[[resources]]
+
+
+DeBERTa를 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰해 드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+
+
+
+- DeBERTa와 [DeepSpeed를 이용해서 대형 모델 학습을 가속시키는](https://huggingface.co/blog/accelerate-deepspeed) 방법에 대한 포스트.
+- DeBERTa와 [머신러닝으로 한층 향상된 고객 서비스](https://huggingface.co/blog/supercharge-customer-service-with-machine-learning)에 대한 블로그 포스트.
+- [`DebertaForSequenceClassification`]는 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-classification)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb)에서 지원됩니다.
+- [`TFDebertaForSequenceClassification`]는 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/text-classification)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification-tf.ipynb)에서 지원됩니다.
+- [텍스트 분류 작업 가이드](../tasks/sequence_classification)
+
+
+
+- [`DebertaForTokenClassification`]는 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/token-classification)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb)에서 지원합니다.
+- [`TFDebertaForTokenClassification`]는 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/token-classification)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification-tf.ipynb)에서 지원합니다.
+- 🤗 Hugging Face 코스의 [토큰 분류](https://huggingface.co/course/chapter7/2?fw=pt) 장.
+- 🤗 Hugging Face 코스의 [BPE(Byte-Pair Encoding) 토큰화](https://huggingface.co/course/chapter6/5?fw=pt) 장.
+- [토큰 분류 작업 가이드](../tasks/token_classification)
+
+
+
+- [`DebertaForMaskedLM`]는 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/language-modeling#robertabertdistilbert-and-masked-language-modeling)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)에서 지원합니다.
+- [`TFDebertaForMaskedLM`]은 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/language-modeling#run_mlmpy)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)에서 지원합니다.
+- 🤗 Hugging Face 코스의 [마스크 언어 모델링](https://huggingface.co/course/chapter7/3?fw=pt) 장.
+- [마스크 언어 모델링 작업 가이드](../tasks/masked_language_modeling)
+
+
+
+- [`DebertaForQuestionAnswering`]은 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb)에서 지원합니다.
+- [`TFDebertaForQuestionAnswering`]는 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/question-answering)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering-tf.ipynb)에서 지원합니다.
+- 🤗 Hugging Face 코스의 [질의응답(Question answering)](https://huggingface.co/course/chapter7/7?fw=pt) 장.
+- [질의응답 작업 가이드](../tasks/question_answering)
+
+## DebertaConfig[[transformers.DebertaConfig]]
+
+[[autodoc]] DebertaConfig
+
+## DebertaTokenizer[[transformers.DebertaTokenizer]]
+
+[[autodoc]] DebertaTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## DebertaTokenizerFast[[transformers.DebertaTokenizerFast]]
+
+[[autodoc]] DebertaTokenizerFast
+ - build_inputs_with_special_tokens
+ - create_token_type_ids_from_sequences
+
+
+
+
+## DebertaModel[[transformers.DebertaModel]]
+
+[[autodoc]] DebertaModel
+ - forward
+
+## DebertaPreTrainedModel[[transformers.DebertaPreTrainedModel]]
+
+[[autodoc]] DebertaPreTrainedModel
+
+## DebertaForMaskedLM[[transformers.DebertaForMaskedLM]]
+
+[[autodoc]] DebertaForMaskedLM
+ - forward
+
+## DebertaForSequenceClassification[[transformers.DebertaForSequenceClassification]]
+
+[[autodoc]] DebertaForSequenceClassification
+ - forward
+
+## DebertaForTokenClassification[[transformers.DebertaForTokenClassification]]
+
+[[autodoc]] DebertaForTokenClassification
+ - forward
+
+## DebertaForQuestionAnswering[[transformers.DebertaForQuestionAnswering]]
+
+[[autodoc]] DebertaForQuestionAnswering
+ - forward
+
+
+
+
+## TFDebertaModel[[transformers.TFDebertaModel]]
+
+[[autodoc]] TFDebertaModel
+ - call
+
+## TFDebertaPreTrainedModel[[transformers.TFDebertaPreTrainedModel]]
+
+[[autodoc]] TFDebertaPreTrainedModel
+ - call
+
+## TFDebertaForMaskedLM[[transformers.TFDebertaForMaskedLM]]
+
+[[autodoc]] TFDebertaForMaskedLM
+ - call
+
+## TFDebertaForSequenceClassification[[transformers.TFDebertaForSequenceClassification]]
+
+[[autodoc]] TFDebertaForSequenceClassification
+ - call
+
+## TFDebertaForTokenClassification[[transformers.TFDebertaForTokenClassification]]
+
+[[autodoc]] TFDebertaForTokenClassification
+ - call
+
+## TFDebertaForQuestionAnswering[[transformers.TFDebertaForQuestionAnswering]]
+
+[[autodoc]] TFDebertaForQuestionAnswering
+ - call
+
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/encoder-decoder.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/encoder-decoder.md
new file mode 100644
index 0000000000000000000000000000000000000000..c5c553561395361bf2ea588f50a5bb3756d213a8
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/encoder-decoder.md
@@ -0,0 +1,167 @@
+
+
+# 인코더-디코더 모델[[Encoder Decoder Models]]
+
+## 개요[[Overview]]
+
+[`EncoderDecoderModel`]은 사전 학습된 자동 인코딩(autoencoding) 모델을 인코더로, 사전 학습된 자가 회귀(autoregressive) 모델을 디코더로 활용하여 시퀀스-투-시퀀스(sequence-to-sequence) 모델을 초기화하는 데 이용됩니다.
+
+사전 학습된 체크포인트를 활용해 시퀀스-투-시퀀스 모델을 초기화하는 것이 시퀀스 생성(sequence generation) 작업에 효과적이라는 점이 Sascha Rothe, Shashi Narayan, Aliaksei Severyn의 논문 [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461)에서 입증되었습니다.
+
+[`EncoderDecoderModel`]이 학습/미세 조정된 후에는 다른 모델과 마찬가지로 저장/불러오기가 가능합니다. 자세한 사용법은 예제를 참고하세요.
+
+이 아키텍처의 한 가지 응용 사례는 두 개의 사전 학습된 [`BertModel`]을 각각 인코더와 디코더로 활용하여 요약 모델(summarization model)을 구축하는 것입니다. 이는 Yang Liu와 Mirella Lapata의 논문 [Text Summarization with Pretrained Encoders](https://arxiv.org/abs/1908.08345)에서 제시된 바 있습니다.
+
+## 모델 설정에서 `EncoderDecoderModel`을 무작위 초기화하기[[Randomly initializing `EncoderDecoderModel` from model configurations.]]
+
+[`EncoderDecoderModel`]은 인코더와 디코더 설정(config)을 기반으로 무작위 초기화를 할 수 있습니다. 아래 예시는 [`BertModel`] 설정을 인코더로, 기본 [`BertForCausalLM`] 설정을 디코더로 사용하는 방법을 보여줍니다.
+
+```python
+>>> from transformers import BertConfig, EncoderDecoderConfig, EncoderDecoderModel
+
+>>> config_encoder = BertConfig()
+>>> config_decoder = BertConfig()
+
+>>> config = EncoderDecoderConfig.from_encoder_decoder_configs(config_encoder, config_decoder)
+>>> model = EncoderDecoderModel(config=config)
+```
+
+## 사전 학습된 인코더와 디코더로 `EncoderDecoderModel` 초기화하기[[Initialising `EncoderDecoderModel` from a pretrained encoder and a pretrained decoder.]]
+
+[`EncoderDecoderModel`]은 사전 학습된 인코더 체크포인트와 사전 학습된 디코더 체크포인트를 사용해 초기화할 수 있습니다. BERT와 같은 모든 사전 학습된 자동 인코딩(auto-encoding) 모델은 인코더로 활용할 수 있으며, GPT2와 같은 자가 회귀(autoregressive) 모델이나 BART의 디코더와 같이 사전 학습된 시퀀스-투-시퀀스 디코더 모델을 디코더로 사용할 수 있습니다. 디코더로 선택한 아키텍처에 따라 교차 어텐션(cross-attention) 레이어가 무작위로 초기화될 수 있습니다. 사전 학습된 인코더와 디코더 체크포인트를 이용해 [`EncoderDecoderModel`]을 초기화하려면, 모델을 다운스트림 작업에 대해 미세 조정(fine-tuning)해야 합니다. 이에 대한 자세한 내용은 [the *Warm-starting-encoder-decoder blog post*](https://huggingface.co/blog/warm-starting-encoder-decoder)에 설명되어 있습니다. 이 작업을 위해 `EncoderDecoderModel` 클래스는 [`EncoderDecoderModel.from_encoder_decoder_pretrained`] 메서드를 제공합니다.
+
+
+```python
+>>> from transformers import EncoderDecoderModel, BertTokenizer
+
+>>> tokenizer = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+>>> model = EncoderDecoderModel.from_encoder_decoder_pretrained("google-bert/bert-base-uncased", "google-bert/bert-base-uncased")
+```
+
+## 기존 `EncoderDecoderModel` 체크포인트 불러오기 및 추론하기[[Loading an existing `EncoderDecoderModel` checkpoint and perform inference.]]
+
+`EncoderDecoderModel` 클래스의 미세 조정(fine-tuned)된 체크포인트를 불러오려면, Transformers의 다른 모델 아키텍처와 마찬가지로 [`EncoderDecoderModel`]에서 제공하는 `from_pretrained(...)`를 사용할 수 있습니다.
+
+추론을 수행하려면 [`generate`] 메서드를 활용하여 텍스트를 자동 회귀(autoregressive) 방식으로 생성할 수 있습니다. 이 메서드는 탐욕 디코딩(greedy decoding), 빔 서치(beam search), 다항 샘플링(multinomial sampling) 등 다양한 디코딩 방식을 지원합니다.
+
+```python
+>>> from transformers import AutoTokenizer, EncoderDecoderModel
+
+>>> # 미세 조정된 seq2seq 모델과 대응하는 토크나이저 가져오기
+>>> model = EncoderDecoderModel.from_pretrained("patrickvonplaten/bert2bert_cnn_daily_mail")
+>>> tokenizer = AutoTokenizer.from_pretrained("patrickvonplaten/bert2bert_cnn_daily_mail")
+
+>>> # let's perform inference on a long piece of text
+>>> ARTICLE_TO_SUMMARIZE = (
+... "PG&E stated it scheduled the blackouts in response to forecasts for high winds "
+... "amid dry conditions. The aim is to reduce the risk of wildfires. Nearly 800 thousand customers were "
+... "scheduled to be affected by the shutoffs which were expected to last through at least midday tomorrow."
+... )
+>>> input_ids = tokenizer(ARTICLE_TO_SUMMARIZE, return_tensors="pt").input_ids
+
+>>> # 자기회귀적으로 요약 생성 (기본적으로 그리디 디코딩 사용)
+>>> generated_ids = model.generate(input_ids)
+>>> generated_text = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+>>> print(generated_text)
+nearly 800 thousand customers were affected by the shutoffs. the aim is to reduce the risk of wildfires. nearly 800, 000 customers were expected to be affected by high winds amid dry conditions. pg & e said it scheduled the blackouts to last through at least midday tomorrow.
+```
+
+## `TFEncoderDecoderModel`에 Pytorch 체크포인트 불러오기[[Loading a PyTorch checkpoint into `TFEncoderDecoderModel`.]]
+
+[`TFEncoderDecoderModel.from_pretrained`] 메서드는 현재 Pytorch 체크포인트를 사용한 모델 초기화를 지원하지 않습니다. 이 메서드에 `from_pt=True`를 전달하면 예외(exception)가 발생합니다. 특정 인코더-디코더 모델에 대한 Pytorch 체크포인트만 존재하는 경우, 다음과 같은 해결 방법을 사용할 수 있습니다:
+
+```python
+>>> # 파이토치 체크포인트에서 로드하는 해결 방법
+>>> from transformers import EncoderDecoderModel, TFEncoderDecoderModel
+
+>>> _model = EncoderDecoderModel.from_pretrained("patrickvonplaten/bert2bert-cnn_dailymail-fp16")
+
+>>> _model.encoder.save_pretrained("./encoder")
+>>> _model.decoder.save_pretrained("./decoder")
+
+>>> model = TFEncoderDecoderModel.from_encoder_decoder_pretrained(
+... "./encoder", "./decoder", encoder_from_pt=True, decoder_from_pt=True
+... )
+>>> # 이 부분은 특정 모델의 구체적인 세부사항을 복사할 때에만 사용합니다.
+>>> model.config = _model.config
+```
+
+## 학습[[Training]]
+
+모델이 생성된 후에는 BART, T5 또는 기타 인코더-디코더 모델과 유사한 방식으로 미세 조정(fine-tuning)할 수 있습니다.
+보시다시피, 손실(loss)을 계산하려면 단 2개의 입력만 필요합니다: `input_ids`(입력 시퀀스를 인코딩한 `input_ids`)와 `labels`(목표 시퀀스를 인코딩한 `input_ids`).
+
+```python
+>>> from transformers import BertTokenizer, EncoderDecoderModel
+
+>>> tokenizer = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+>>> model = EncoderDecoderModel.from_encoder_decoder_pretrained("google-bert/bert-base-uncased", "google-bert/bert-base-uncased")
+
+>>> model.config.decoder_start_token_id = tokenizer.cls_token_id
+>>> model.config.pad_token_id = tokenizer.pad_token_id
+
+>>> input_ids = tokenizer(
+... "The tower is 324 metres (1,063 ft) tall, about the same height as an 81-storey building, and the tallest structure in Paris. Its base is square, measuring 125 metres (410 ft) on each side.During its construction, the Eiffel Tower surpassed the Washington Monument to become the tallest man-made structure in the world, a title it held for 41 years until the Chrysler Building in New York City was finished in 1930. It was the first structure to reach a height of 300 metres. Due to the addition of a broadcasting aerial at the top of the tower in 1957, it is now taller than the Chrysler Building by 5.2 metres (17 ft).Excluding transmitters, the Eiffel Tower is the second tallest free-standing structure in France after the Millau Viaduct.",
+... return_tensors="pt",
+... ).input_ids
+
+>>> labels = tokenizer(
+... "the eiffel tower surpassed the washington monument to become the tallest structure in the world. it was the first structure to reach a height of 300 metres in paris in 1930. it is now taller than the chrysler building by 5. 2 metres ( 17 ft ) and is the second tallest free - standing structure in paris.",
+... return_tensors="pt",
+... ).input_ids
+
+>>> # forward 함수가 자동으로 적합한 decoder_input_ids를 생성합니다.
+>>> loss = model(input_ids=input_ids, labels=labels).loss
+```
+훈련에 대한 자세한 내용은 [colab](https://colab.research.google.com/drive/1WIk2bxglElfZewOHboPFNj8H44_VAyKE?usp=sharing#scrollTo=ZwQIEhKOrJpl) 노트북을 참조하세요.
+
+이 모델은 [thomwolf](https://github.com/thomwolf)가 기여했으며, 이 모델에 대한 TensorFlow 및 Flax 버전은 [ydshieh](https://github.com/ydshieh)가 기여했습니다.
+
+
+## EncoderDecoderConfig
+
+[[autodoc]] EncoderDecoderConfig
+
+
+
+
+## EncoderDecoderModel
+
+[[autodoc]] EncoderDecoderModel
+ - forward
+ - from_encoder_decoder_pretrained
+
+
+
+
+## TFEncoderDecoderModel
+
+[[autodoc]] TFEncoderDecoderModel
+ - call
+ - from_encoder_decoder_pretrained
+
+
+
+
+## FlaxEncoderDecoderModel
+
+[[autodoc]] FlaxEncoderDecoderModel
+ - __call__
+ - from_encoder_decoder_pretrained
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/esm.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/esm.md
new file mode 100644
index 0000000000000000000000000000000000000000..6ea1191dabe0bae8306f981b7bffe9dfd8edbd94
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/esm.md
@@ -0,0 +1,115 @@
+
+
+# ESM [[esm]]
+
+## 개요 [[overview]]
+
+이 페이지는 Meta AI의 Fundamental AI Research 팀에서 제공하는 Transformer 단백질 언어 모델에 대한 코드와 사전 훈련된 가중치를 제공합니다. 여기에는 최첨단인 ESMFold와 ESM-2, 그리고 이전에 공개된 ESM-1b와 ESM-1v가 포함됩니다. Transformer 단백질 언어 모델은 Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott, C. Lawrence Zitnick, Jerry Ma, Rob Fergus의 논문 [Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118)에서 소개되었습니다. 이 논문의 첫 번째 버전은 2019년에 [출판 전 논문](https://www.biorxiv.org/content/10.1101/622803v1?versioned=true) 형태로 공개되었습니다.
+
+ESM-2는 다양한 구조 예측 작업에서 테스트된 모든 단일 시퀀스 단백질 언어 모델을 능가하며, 원자 수준의 구조 예측을 가능하게 합니다. 이 모델은 Zeming Lin, Halil Akin, Roshan Rao, Brian Hie, Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido, Alexander Rives의 논문 [Language models of protein sequences at the scale of evolution enable accurate structure prediction](https://doi.org/10.1101/2022.07.20.500902)에서 공개되었습니다.
+
+이 논문에서 함께 소개된 ESMFold는 ESM-2 스템을 사용하며, 최첨단의 정확도로 단백질 접힘 구조를 예측할 수 있는 헤드를 갖추고 있습니다. [AlphaFold2](https://www.nature.com/articles/s41586-021-03819-2)와 달리, 이는 대형 사전 훈련된 단백질 언어 모델 스템의 토큰 임베딩에 의존하며, 추론 시 다중 시퀀스 정렬(MSA) 단계를 수행하지 않습니다. 이는 ESMFold 체크포인트가 완전히 "독립적"이며, 예측을 위해 알려진 단백질 시퀀스와 구조의 데이터베이스, 그리고 그와 관련 외부 쿼리 도구를 필요로 하지 않는다는 것을 의미합니다. 그리고 그 결과, 훨씬 빠릅니다.
+
+"Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences"의 초록은 다음과 같습니다:
+
+*인공지능 분야에서는 대규모의 데이터와 모델 용량을 갖춘 비지도 학습의 조합이 표현 학습과 통계적 생성에서 주요한 발전을 이끌어냈습니다. 생명 과학에서는 시퀀싱 기술의 성장이 예상되며, 자연 시퀀스 다양성에 대한 전례 없는 데이터가 나올 것으로 기대됩니다. 진화적 단계에서 볼 때, 단백질 언어 모델링은 생물학을 위한 예측 및 생성 인공지능을 향한 논리적인 단계에 있습니다. 이를 위해 우리는 진화적 다양성을 아우르는 2억 5천만 개의 단백질 시퀀스에서 추출한 860억 개의 아미노산에 대해 심층 컨텍스트 언어 모델을 비지도 학습으로 훈련합니다. 그 결과 모델은 그 표현에서 생물학적 속성에 대한 정보를 포함합니다. 이 표현은 시퀀스 데이터만으로 학습됩니다. 학습된 표현 공간은 아미노산의 생화학적 특성 수준에서부터 단백질의 원거리 상동성까지 구조를 반영하는 다중 규모의 조직을 가지고 있습니다. 이 표현에는 2차 및 3차 구조에 대한 정보가 인코딩되어 있으며, 선형 전사에 의해 식별 될 수 있습니다. 표현 학습은 돌연변이에 의한 효과와 2차 구조의 최첨단 지도 예측을 가능하게 하고, 넓은 범위의 접촉 부위 예측을 위한 최첨단 특징을 향상시킵니다.*
+
+"Language models of protein sequences at the scale of evolution enable accurate structure prediction"의 초록은 다음과 같습니다:
+
+*대형 언어 모델은 최근 규모가 커짐에 따라 긴급한 기능을 개발하여 단순한 패턴 매칭을 넘어 더 높은 수준의 추론을 수행하고 생생한 이미지와 텍스트를 생성하는 것으로 나타났습니다. 더 작은 규모에서 훈련된 단백질 시퀀스의 언어 모델이 연구되었지만, 그들이 규모가 커짐에 따라 생물학에 대해 무엇을 배우는지는 거의 알려져 있지 않습니다. 이 연구에서 우리는 현재까지 평가된 가장 큰 150억 개의 매개변수를 가진 모델을 훈련합니다. 우리는 모델이 규모가 커짐에 따라 단일 아미노산의 해상도로 단백질의 3차원 구조를 예측할 수 있는 정보를 학습한다는 것을 발견했습니다. 우리는 개별 단백질 시퀀스로부터 직접 고정밀 원자 수준의 엔드-투-엔드 구조 예측을 하기 위한 ESMFold를 제시합니다. ESMFold는 언어 모델에 잘 이해되는 낮은 퍼플렉서티를 가진 시퀀스에 대해 AlphaFold2와 RoseTTAFold와 유사한 정확도를 가지고 있습니다. ESMFold의 추론은 AlphaFold2보다 한 자릿수 빠르며, 메타게놈 단백질의 구조적 공간을 실용적인 시간 내에 탐색할 수 있게 합니다.*
+
+원본 코드는 [여기](https://github.com/facebookresearch/esm)에서 찾을 수 있으며, Meta AI의 Fundamental AI Research 팀에서 개발되었습니다. ESM-1b, ESM-1v, ESM-2는 [jasonliu](https://huggingface.co/jasonliu)와 [Matt](https://huggingface.co/Rocketknight1)에 의해 HuggingFace에 기여되었습니다.
+
+ESMFold는 [Matt](https://huggingface.co/Rocketknight1)와 [Sylvain](https://huggingface.co/sgugger)에 의해 HuggingFace에 기여되었으며, 이 과정에서 많은 도움을 준 Nikita Smetanin, Roshan Rao, Tom Sercu에게 큰 감사를 드립니다!
+
+## 사용 팁 [[usage-tips]]
+
+- ESM 모델은 마스크드 언어 모델링(MLM) 목표로 훈련되었습니다.
+- HuggingFace의 ESMFold 포트는 [openfold](https://github.com/aqlaboratory/openfold) 라이브러리의 일부를 사용합니다. `openfold` 라이브러리는 Apache License 2.0에 따라 라이선스가 부여됩니다.
+
+## 리소스 [[resources]]
+
+- [텍스트 분류 작업 가이드](../tasks/sequence_classification)
+- [토큰 분류 작업 가이드](../tasks/token_classification)
+- [마스킹드 언어 모델링 작업 가이드](../tasks/masked_language_modeling)
+
+## EsmConfig [[transformers.EsmConfig]]
+
+[[autodoc]] EsmConfig
+ - all
+
+## EsmTokenizer [[transformers.EsmTokenizer]]
+
+[[autodoc]] EsmTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+
+
+
+## EsmModel [[transformers.EsmModel]]
+
+[[autodoc]] EsmModel
+ - forward
+
+## EsmForMaskedLM [[transformers.EsmForMaskedLM]]
+
+[[autodoc]] EsmForMaskedLM
+ - forward
+
+## EsmForSequenceClassification [[transformers.EsmForSequenceClassification]]
+
+[[autodoc]] EsmForSequenceClassification
+ - forward
+
+## EsmForTokenClassification [[transformers.EsmForTokenClassification]]
+
+[[autodoc]] EsmForTokenClassification
+ - forward
+
+## EsmForProteinFolding [[transformers.EsmForProteinFolding]]
+
+[[autodoc]] EsmForProteinFolding
+ - forward
+
+
+
+
+## TFEsmModel [[transformers.TFEsmModel]]
+
+[[autodoc]] TFEsmModel
+ - call
+
+## TFEsmForMaskedLM [[transformers.TFEsmForMaskedLM]]
+
+[[autodoc]] TFEsmForMaskedLM
+ - call
+
+## TFEsmForSequenceClassification [[transformers.TFEsmForSequenceClassification]]
+
+[[autodoc]] TFEsmForSequenceClassification
+ - call
+
+## TFEsmForTokenClassification [[transformers.TFEsmForTokenClassification]]
+
+[[autodoc]] TFEsmForTokenClassification
+ - call
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/gemma.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/gemma.md
new file mode 100644
index 0000000000000000000000000000000000000000..25fe6f1c772950ec5bab3d0f3a9850666d90b94f
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/gemma.md
@@ -0,0 +1,76 @@
+
+
+# Gemma [[gemma]]
+
+## 개요 [[overview]]
+
+Gemma 모델은 Google의 Gemma 팀이 작성한 [Gemma: Open Models Based on Gemini Technology and Research](https://blog.google/technology/developers/gemma-open-models/)에서 제안되었습니다.
+
+Gemma 모델은 6조 토큰으로 학습되었으며, 2b와 7b의 두 가지 버전으로 출시되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*이 연구는 언어 이해, 추론 및 안전성에 대한 학술 벤치마크에서 뛰어난 성능을 보이는 새로운 오픈 언어 모델 계열인 Gemma를 소개합니다. 우리는 두 가지 크기(20억 및 70억 매개변수)의 모델을 출시하며, 사전 학습된 체크포인트와 미세 조정된 체크포인트를 모두 제공합니다. Gemma는 18개의 텍스트 기반 작업 중 11개에서 유사한 크기의 오픈 모델을 능가하며, 우리는 모델 개발에 대한 상세한 설명과 함께 안전성과 책임 측면에 대한 종합적인 평가를 제공합니다. 우리는 LLM의 책임감 있는 공개가 최첨단 모델의 안전성을 향상시키고 다음 세대의 LLM 혁신을 가능하게 하는 데 중요하다고 믿습니다.*
+
+팁:
+
+- 원본 체크포인트는 변환 스크립트 `src/transformers/models/gemma/convert_gemma_weights_to_hf.py`를 사용하여 변환할 수 있습니다.
+
+이 모델은 [Arthur Zucker](https://huggingface.co/ArthurZ), [Younes Belkada](https://huggingface.co/ybelkada), [Sanchit Gandhi](https://huggingface.co/sanchit-gandhi), [Pedro Cuenca](https://huggingface.co/pcuenq)가 기여했습니다.
+
+## GemmaConfig [[transformers.GemmaConfig]]
+
+[[autodoc]] GemmaConfig
+
+## GemmaTokenizer [[transformers.GemmaTokenizer]]
+
+[[autodoc]] GemmaTokenizer
+
+
+## GemmaTokenizerFast [[transformers.GemmaTokenizerFast]]
+
+[[autodoc]] GemmaTokenizerFast
+
+## GemmaModel [[transformers.GemmaModel]]
+
+[[autodoc]] GemmaModel
+ - forward
+
+## GemmaForCausalLM [[transformers.GemmaForCausalLM]]
+
+[[autodoc]] GemmaForCausalLM
+ - forward
+
+## GemmaForSequenceClassification [[transformers.GemmaForSequenceClassification]]
+
+[[autodoc]] GemmaForSequenceClassification
+ - forward
+
+## GemmaForTokenClassification [[transformers.GemmaForTokenClassification]]
+
+[[autodoc]] GemmaForTokenClassification
+ - forward
+
+## FlaxGemmaModel [[transformers.FlaxGemmaModel]]
+
+[[autodoc]] FlaxGemmaModel
+ - __call__
+
+## FlaxGemmaForCausalLM [[transformers.FlaxGemmaForCausalLM]]
+
+[[autodoc]] FlaxGemmaForCausalLM
+ - __call__
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/gemma2.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/gemma2.md
new file mode 100644
index 0000000000000000000000000000000000000000..6bffec616c6e97d853a8e4d0b8f279bf1033d668
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/gemma2.md
@@ -0,0 +1,63 @@
+
+
+
+# Gemma2 [[gemma2]]
+
+## 개요 [[overview]]
+
+Gemma2 모델은 Google의 Gemma2 팀이 작성한 [Gemma2: Open Models Based on Gemini Technology and Research](https://blog.google/technology/developers/google-gemma-2/)에서 제안되었습니다.
+파라미터 크기가 각각 90억(9B)과 270억(27B)인 두 가지 Gemma2 모델이 출시되었습니다.
+
+블로그 게시물의 초록은 다음과 같습니다:
+
+*이제 우리는 전 세계의 연구자와 개발자들에게 Gemma 2를 공식적으로 출시합니다. 90억(9B)과 270억(27B) 파라미터 크기로 제공되는 Gemma 2는 1세대보다 더 높은 성능과 추론 효율성을 제공하며, 상당한 안전성 향상을 포함하고 있습니다. 사실 270억 규모의 모델은 크기가 두 배 이상인 모델과 비교해도 경쟁력 있는 대안을 제공하며, 이는 작년 12월까지만 해도 독점 모델에서만 가능했던 성능을 제공합니다.*
+
+팁:
+
+- 원본 체크포인트는 변환 스크립트 `src/transformers/models/Gemma2/convert_Gemma2_weights_to_hf.py`를 사용하여 변환할 수 있습니다.
+
+
+
+- Gemma2는 매 두 번째 레이어마다 슬라이딩 윈도우 어텐션을 사용하므로 [`~DynamicCache`] 또는 텐서의 튜플과 같은 일반적인 kv 캐싱에는 적합하지 않습니다. Gemma2의 forward 호출에서 캐싱을 활성화하려면 [`~HybridCache`] 인스턴스를 초기화하고 이를 `past_key_values`로 forward 호출에 전달해야 합니다. 또한 `past_key_values`에 이미 이전의 키와 값이 포함되어 있다면 `cache_position`도 준비해야 합니다.
+
+
+
+이 모델은 [Arthur Zucker](https://huggingface.co/ArthurZ), [Pedro Cuenca](https://huggingface.co/pcuenq), [Tom Arsen]()이 기여했습니다.
+
+## Gemma2Config [[transformers.Gemma2Config]]
+
+[[autodoc]] Gemma2Config
+
+## Gemma2Model [[transformers.Gemma2Model]]
+
+[[autodoc]] Gemma2Model
+ - forward
+
+## Gemma2ForCausalLM [[transformers.Gemma2ForCausalLM]]
+
+[[autodoc]] Gemma2ForCausalLM
+ - forward
+
+## Gemma2ForSequenceClassification [[transformers.Gemma2ForSequenceClassification]]
+
+[[autodoc]] Gemma2ForSequenceClassification
+ - forward
+
+## Gemma2ForTokenClassification [[transformers.Gemma2ForTokenClassification]]
+
+[[autodoc]] Gemma2ForTokenClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/gpt_neox_japanese.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/gpt_neox_japanese.md
new file mode 100644
index 0000000000000000000000000000000000000000..13fb656dd50e9463740e1ea273bfcb9073ecd1e1
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/gpt_neox_japanese.md
@@ -0,0 +1,76 @@
+
+
+# GPT-NeoX-Japanese [[gpt-neox-japanese]]
+
+## 개요 [[overview]]
+
+
+일본어를 위한 자동회귀 언어 모델인 GPT-NeoX-Japanese를 소개합니다. 이 모델은 [https://github.com/EleutherAI/gpt-neox](https://github.com/EleutherAI/gpt-neox)에서 학습되었습니다. 일본어는 많은 어휘와 히라가나, 가타카나, 한자의 조합으로 이루어진 독특한 언어입니다. 이러한 일본어의 독특한 구조를 해결하기 위해 [특수 서브워드 토크나이저](https://github.com/tanreinama/Japanese-BPEEncoder_V2)를 사용했습니다. 이 유용한 토크나이저를 오픈소스로 제공해 준 *tanreinama*에게 매우 감사드립니다.
+
+이 모델은 Google의 [PaLM](https://ai.googleblog.com/2022/04/pathways-language-model-palm-scaling-to.html) 연구 권장 사항을 따르며, 트랜스포머 블록에서 편향 파라미터를 제거하여 모델 성능을 향상시켰습니다. 자세한 내용은 [이 기사](https://medium.com/ml-abeja/training-a-better-gpt-2-93b157662ae4)를 참조하세요.
+
+모델 개발은 [ABEJA, Inc.](https://www.abejainc.com/)의 [신야 오타니](https://github.com/SO0529), [타카요시 마카베](https://github.com/spider-man-tm), [안주 아로라](https://github.com/Anuj040), [쿄 하토리](https://github.com/go5paopao)에 의해 주도되었습니다. 이 모델 개발 활동에 대한 자세한 내용은 [여기](https://tech-blog.abeja.asia/entry/abeja-gpt-project-202207)를 참조하세요.
+
+
+
+### 사용 예시 [[usage-example]]
+
+`generate()` 메서드를 사용하면 GPT NeoX Japanese 모델을 통해 텍스트를 생성할 수 있습니다.
+
+```python
+>>> from transformers import GPTNeoXJapaneseForCausalLM, GPTNeoXJapaneseTokenizer
+
+>>> model = GPTNeoXJapaneseForCausalLM.from_pretrained("abeja/gpt-neox-japanese-2.7b")
+>>> tokenizer = GPTNeoXJapaneseTokenizer.from_pretrained("abeja/gpt-neox-japanese-2.7b")
+
+>>> prompt = "人とAIが協調するためには、"
+
+>>> input_ids = tokenizer(prompt, return_tensors="pt").input_ids
+
+>>> gen_tokens = model.generate(
+... input_ids,
+... do_sample=True,
+... temperature=0.9,
+... max_length=100,
+... )
+>>> gen_text = tokenizer.batch_decode(gen_tokens, skip_special_tokens=True)[0]
+
+>>> print(gen_text)
+人とAIが協調するためには、AIと人が共存し、AIを正しく理解する必要があります。
+```
+
+## 자료 [[resources]]
+
+- [일상 언어 모델링 작업 가이드 ](../tasks/language_modeling)
+
+## GPTNeoXJapanese 설정 (GPTNeoXJapaneseConfig) [[transformers.GPTNeoXJapaneseConfig]]
+
+[[autodoc]] GPTNeoXJapaneseConfig
+
+## GPTNeoXJapanese토큰화 (GPTNeoXJapaneseTokenizer) [[transformers.GPTNeoXJapaneseTokenizer]]
+
+[[autodoc]] GPTNeoXJapaneseTokenizer
+
+## GPTNeoXJapaneseModel [[transformers.GPTNeoXJapaneseModel]]
+
+[[autodoc]] GPTNeoXJapaneseModel
+ - forward
+
+## 일상 LLM 을 위한 GPTNeoXJapanese(GPTNeoXJapaneseForCausalLM) [[transformers.GPTNeoXJapaneseForCausalLM]]
+
+[[autodoc]] GPTNeoXJapaneseForCausalLM
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/graphormer.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/graphormer.md
new file mode 100644
index 0000000000000000000000000000000000000000..fc6aa2c9e2f7eef354a1ae4835f12d1a883f4938
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/graphormer.md
@@ -0,0 +1,52 @@
+
+
+# Graphormer[[graphormer]]
+
+
+
+이 모델은 유지 보수 모드로만 운영되며, 코드를 변경하는 새로운 PR(Pull Request)은 받지 않습니다.
+이 모델을 실행하는 데 문제가 발생한다면, 이 모델을 지원하는 마지막 버전인 v4.40.2를 다시 설치해 주세요. 다음 명령어를 실행하여 재설치할 수 있습니다: `pip install -U transformers==4.40.2`.
+
+
+
+## 개요[[overview]]
+
+Graphormer 모델은 Chengxuan Ying, Tianle Cai, Shengjie Luo, Shuxin Zheng, Guolin Ke, Di He, Yanming Shen, Tie-Yan Liu가 제안한 [트랜스포머가 그래프 표현에 있어서 정말 약할까?](https://arxiv.org/abs/2106.05234) 라는 논문에서 소개되었습니다. Graphormer는 그래프 트랜스포머 모델입니다. 텍스트 시퀀스 대신 그래프에서 계산을 수행할 수 있도록 수정되었으며, 전처리와 병합 과정에서 임베딩과 관심 특성을 생성한 후 수정된 어텐션을 사용합니다.
+
+해당 논문의 초록입니다:
+
+*트랜스포머 아키텍처는 자연어 처리와 컴퓨터 비전 등 많은 분야에서 지배적인 선택을 받고 있는 아키텍처 입니다. 그러나 그래프 수준 예측 리더보드 상에서는 주류 GNN 변형모델들에 비해 경쟁력 있는 성능을 달성하지 못했습니다. 따라서 트랜스포머가 그래프 표현 학습에서 어떻게 잘 수행될 수 있을지는 여전히 미스터리였습니다. 본 논문에서는 Graphormer를 제시함으로써 이 미스터리를 해결합니다. Graphormer는 표준 트랜스포머 아키텍처를 기반으로 구축되었으며, 특히 최근의 OpenGraphBenchmark Large-Scale Challenge(OGB-LSC)의 광범위한 그래프 표현 학습 작업에서 탁월한 결과를 얻을 수 있었습니다. 그래프에서 트랜스포머를 활용하는데 핵심은 그래프의 구조적 정보를 모델에 효과적으로 인코딩하는 것입니다. 이를 위해 우리는 Graphormer가 그래프 구조 데이터를 더 잘 모델링할 수 있도록 돕는 몇 가지 간단하면서도 효과적인 구조적 인코딩 방법을 제안합니다. 또한, 우리는 Graphormer의 표현을 수학적으로 특성화하고, 그래프의 구조적 정보를 인코딩하는 우리의 방식으로 많은 인기 있는 GNN 변형모델들이 Graphormer의 특수한 경우로 포함될 수 있음을 보여줍니다.*
+
+이 모델은 [clefourrier](https://huggingface.co/clefourrier)가 기여했습니다. 원본 코드는 [이곳](https://github.com/microsoft/Graphormer)에서 확인할 수 있습니다.
+
+## 사용 팁[[usage-tips]]
+
+이 모델은 큰 그래프(100개 이상의 노드개수/엣지개수)에서는 메모리 사용량이 폭발적으로 증가하므로 잘 작동하지 않습니다. 대안으로 배치 크기를 줄이거나, RAM을 늘리거나 또는 algos_graphormer.pyx 파일의 `UNREACHABLE_NODE_DISTANCE` 매개변수를 줄이는 방법도 있지만, 700개 이상의 노드개수/엣지개수를 처리하기에는 여전히 어려울 것입니다.
+
+이 모델은 토크나이저를 사용하지 않고, 대신 훈련 중에 특별한 콜레이터(collator)를 사용합니다.
+
+## GraphormerConfig[[transformers.GraphormerConfig]]
+
+[[autodoc]] GraphormerConfig
+
+## GraphormerModel[[transformers.GraphormerModel]]
+
+[[autodoc]] GraphormerModel
+ - forward
+
+## GraphormerForGraphClassification[[transformers.GraphormerForGraphClassification]]
+
+[[autodoc]] GraphormerForGraphClassification
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/informer.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/informer.md
new file mode 100644
index 0000000000000000000000000000000000000000..03722545a5625e7340eedb4a64948d366d190fa4
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/informer.md
@@ -0,0 +1,55 @@
+
+
+# Informer[[informer]]
+
+## 개요[[overview]]
+
+The Informer 모델은 Haoyi Zhou, Shanghang Zhang, Jieqi Peng, Shuai Zhang, Jianxin Li, Hui Xiong, Wancai Zhang가 제안한 [Informer: 장기 시퀀스 시계열 예측(LSTF)을 위한 더욱 효율적인 트랜스포머(Beyond Efficient Transformer)](https://arxiv.org/abs/2012.07436)라는 논문에서 소개되었습니다.
+
+이 방법은 확률적 어텐션 메커니즘을 도입하여 "게으른" 쿼리가 아닌 "활성" 쿼리를 선택하고, 희소 트랜스포머를 제공하여 기존 어텐션의 이차적 계산 및 메모리 요구사항을 완화합니다.
+
+해당 논문의 초록입니다:
+
+*실제로 많은 응용프로그램에서는 장기 시퀀스 시계열 예측(LSTF)을 필요로 합니다. LSTF는 출력 - 입력 간 정확한 장기 의존성 결합도를 포착해내는 높은 예측 능력을 모델에 요구합니다. 최근 연구들은 예측 능력을 향상시킬 수 있는 트랜스포머의 잠재력을 보여주고 있습니다. 그러나, 트랜스포머를 LSTF에 직접 적용하지 못하도록 막는 몇 심각한 문제점들이 있습니다. 예로, 이차 시간 복잡도, 높은 메모리 사용량, 인코더-디코더 아키텍처의 본질적 한계를 들 수 있습니다. 이러한 문제를 해결하기 위해 LSTF를 위한 효율적인 트랜스포머 기반 모델인 Informer를 설계했습니다.
+
+Informer의 세가지 독특한 특성:
+(i) ProbSparse 셀프 어텐션 메커니즘으로, 시간 복잡도와 메모리 사용량에서 O(L logL)를 달성하며 시퀀스 의존성 정렬에서 비교 가능한 성능을 보입니다.
+(ii) 셀프 어텐션 증류는 계단식 레이어 입력을 반으로 줄여 지배적인 어텐션을 강조하고 극단적으로 긴 입력 시퀀스를 효율적으로 처리합니다.
+(iii) 생성 스타일 디코더는 개념적으로 단순하지만 장기 시계열 시퀀스를 단계별 방식이 아닌 한 번의 전방 연산으로 예측하여 장기 시퀀스 예측의 추론 속도를 크게 향상시킵니다. 4개의 대규모 데이터셋에 걸친 광범위한 실험은 Informer가 기존 방법들을 크게 능가하며 LSTF 문제에 새로운 해결책을 제공함을 보여줍니다.*
+
+이 모델은 [elisim](https://huggingface.co/elisim)와 [kashif](https://huggingface.co/kashif)가 기여했습니다.
+원본 코드는 [이곳](https://github.com/zhouhaoyi/Informer2020)에서 확인할 수 있습니다.
+
+## 자료[[resources]]
+
+시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+- HuggingFace 블로그에서 Informer 포스트를 확인하세요: [Informer를 활용한 다변량 확률적 시계열 예측](https://huggingface.co/blog/informer)
+
+## InformerConfig[[transformers.InformerConfig]]
+
+[[autodoc]] InformerConfig
+
+## InformerModel[[transformers.InformerModel]]
+
+[[autodoc]] InformerModel
+ - forward
+
+## InformerForPrediction[[transformers.InformerForPrediction]]
+
+[[autodoc]] InformerForPrediction
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/llama.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/llama.md
new file mode 100644
index 0000000000000000000000000000000000000000..282befac213ddd24d7869bc3438bd3b88959f050
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/llama.md
@@ -0,0 +1,117 @@
+
+
+# LLaMA [[llama]]
+
+## 개요 [[overview]]
+
+LLaMA 모델은 Hugo Touvron, Thibaut Lavril, Gautier Izacard, Xavier Martinet, Marie-Anne Lachaux, Timothée Lacroix, Baptiste Rozière, Naman Goyal, Eric Hambro, Faisal Azhar, Aurelien Rodriguez, Armand Joulin, Edouard Grave, Guillaume Lample에 의해 제안된 [LLaMA: Open and Efficient Foundation Language Models](https://arxiv.org/abs/2302.13971)에서 소개되었습니다. 이 모델은 7B에서 65B개의 파라미터까지 다양한 크기의 기초 언어 모델을 모아놓은 것입니다.
+
+논문의 초록은 다음과 같습니다:
+
+*"LLaMA는 7B에서 65B개의 파라미터 수를 가진 기초 언어 모델의 모음입니다. 우리는 수조 개의 토큰으로 모델을 훈련시켰고, 공개적으로 이용 가능한 데이터셋만을 사용하여 최고 수준의 모델을 훈련시킬 수 있음을 보여줍니다. 특히, LLaMA-13B 모델은 대부분의 벤치마크에서 GPT-3 (175B)를 능가하며, LLaMA-65B는 최고 수준의 모델인 Chinchilla-70B와 PaLM-540B에 버금가는 성능을 보입니다. 우리는 모든 모델을 연구 커뮤니티에 공개합니다."*
+
+팁:
+
+- LLaMA 모델의 가중치는 [이 양식](https://docs.google.com/forms/d/e/1FAIpQLSfqNECQnMkycAp2jP4Z9TFX0cGR4uf7b_fBxjY_OjhJILlKGA/viewform?usp=send_form)을 작성하여 얻을 수 있습니다.
+- 가중치를 다운로드한 후에는 이를 [변환 스크립트](https://github.com/huggingface/transformers/blob/main/src/transformers/models/llama/convert_llama_weights_to_hf.py)를 사용하여 Hugging Face Transformers 형식으로 변환해야합니다. 변환 스크립트를 실행하려면 아래의 예시 명령어를 참고하세요:
+
+```bash
+python src/transformers/models/llama/convert_llama_weights_to_hf.py \
+ --input_dir /path/to/downloaded/llama/weights --model_size 7B --output_dir /output/path
+```
+
+- 변환을 하였다면 모델과 토크나이저는 다음과 같이 로드할 수 있습니다:
+
+```python
+from transformers import LlamaForCausalLM, LlamaTokenizer
+
+tokenizer = LlamaTokenizer.from_pretrained("/output/path")
+model = LlamaForCausalLM.from_pretrained("/output/path")
+```
+
+스크립트를 실행하기 위해서는 모델을 float16 정밀도로 전부 로드할 수 있을 만큼의 충분한 CPU RAM이 필요합니다. (가장 큰 버전의 모델이 여러 체크포인트로 나뉘어 있더라도, 각 체크포인트는 모델의 각 가중치의 일부를 포함하고 있기 때문에 모든 체크포인트를 RAM에 로드해야 합니다) 65B 모델의 경우, 총 130GB의 RAM이 필요합니다.
+
+
+- LLaMA 토크나이저는 [sentencepiece](https://github.com/google/sentencepiece)를 기반으로 하는 BPE 모델입니다. sentencepiece의 특징 중 하나는 시퀀스를 디코딩할 때 첫 토큰이 단어의 시작이라면 (예를 들어 "Banana"), 토크나이저는 문자열 앞에 공백을 추가하지 않는다는 것입니다.
+
+이 모델은 [BlackSamorez](https://huggingface.co/BlackSamorez)의 기여와 함께, [zphang](https://huggingface.co/zphang)에 의해 제공되었습니다. Hugging Face에서의 구현 코드는 GPT-NeoX를 기반으로 하며 [여기](https://github.com/EleutherAI/gpt-neox)에서 찾을 수 있고, 저자의 코드 원본은 [여기](https://github.com/facebookresearch/llama)에서 확인할 수 있습니다.
+
+
+원래 LLaMA 모델을 기반으로 Meta AI에서 몇 가지 후속 작업을 발표했습니다:
+
+- **Llama2**: Llama2는 구조적인 몇 가지 수정(Grouped Query Attention)을 통해 개선된 버전이며, 2조 개의 토큰으로 사전 훈련이 되어 있습니다. Llama2에 대한 자세한 내용은 [이 문서](llama2)를 참고하세요.
+
+## 리소스 [[resources]]
+
+LLaMA를 시작하는 데 도움이 될 Hugging Face 및 커뮤니티(🌎로 표시)의 공식 자료 목록입니다. 여기에 자료를 제출하고 싶다면 Pull Request를 올려주세요! 추가할 자료는 기존의 자료와 중복되지 않고 새로운 내용을 보여주는 것이 좋습니다.
+
+
+
+- LLaMA 모델을 텍스트 분류 작업에 적용하기 위한 프롬프트 튜닝 방법에 대한 [노트북](https://colab.research.google.com/github/bigscience-workshop/petals/blob/main/examples/prompt-tuning-sst2.ipynb#scrollTo=f04ba4d2) 🌎
+
+
+
+- [Stack Exchange](https://stackexchange.com/)에서 질문에 답하는 LLaMA를 훈련하는 방법을 위한 [StackLLaMA: RLHF로 LLaMA를 훈련하는 실전 가이드](https://huggingface.co/blog/stackllama#stackllama-a-hands-on-guide-to-train-llama-with-rlhf) 🌎
+
+⚗️ 최적화
+- 제한된 메모리를 가진 GPU에서 xturing 라이브러리를 사용하여 LLaMA 모델을 미세 조정하는 방법에 대한 [노트북](https://colab.research.google.com/drive/1SQUXq1AMZPSLD4mk3A3swUIc6Y2dclme?usp=sharing) 🌎
+
+⚡️ 추론
+- 🤗 PEFT 라이브러리의 PeftModel을 사용하여 LLaMA 모델을 실행하는 방법에 대한 [노트북](https://colab.research.google.com/github/DominguesM/alpaca-lora-ptbr-7b/blob/main/notebooks/02%20-%20Evaluate.ipynb) 🌎
+- LangChain을 사용하여 PEFT 어댑터 LLaMA 모델을 로드하는 방법에 대한 [노트북](https://colab.research.google.com/drive/1l2GiSSPbajVyp2Nk3CFT4t3uH6-5TiBe?usp=sharing) 🌎
+
+🚀 배포
+- 🤗 PEFT 라이브러리와 사용자 친화적인 UI로 LLaMA 모델을 미세 조정하는 방법에 대한 [노트북](https://colab.research.google.com/github/lxe/simple-llama-finetuner/blob/master/Simple_LLaMA_FineTuner.ipynb#scrollTo=3PM_DilAZD8T) 🌎
+- Amazon SageMaker에서 텍스트 생성을 위해 Open-LLaMA 모델을 배포하는 방법에 대한 [노트북](https://github.com/aws/amazon-sagemaker-examples/blob/main/introduction_to_amazon_algorithms/jumpstart-foundation-models/text-generation-open-llama.ipynb) 🌎
+
+## LlamaConfig [[llamaconfig]]
+
+[[autodoc]] LlamaConfig
+
+
+## LlamaTokenizer [[llamatokenizer]]
+
+[[autodoc]] LlamaTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## LlamaTokenizerFast [[llamatokenizerfast]]
+
+[[autodoc]] LlamaTokenizerFast
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - update_post_processor
+ - save_vocabulary
+
+## LlamaModel [[llamamodel]]
+
+[[autodoc]] LlamaModel
+ - forward
+
+
+## LlamaForCausalLM [[llamaforcausallm]]
+
+[[autodoc]] LlamaForCausalLM
+ - forward
+
+## LlamaForSequenceClassification [[llamaforsequenceclassification]]
+
+[[autodoc]] LlamaForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/llama2.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/llama2.md
new file mode 100644
index 0000000000000000000000000000000000000000..5290f2bb7b6f8d39ca6fb4fd1bba98e4f1b449aa
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/llama2.md
@@ -0,0 +1,129 @@
+
+
+# Llama2 [[llama2]]
+
+## 개요 [[overview]]
+
+Llama2 모델은 Hugo Touvron, Louis Martin, Kevin Stone, Peter Albert, Amjad Almahairi, Ya1smine Babaei, Nikolay Bashlykov, Soumya Batra, Prajjwal Bhargava, Shruti Bhosale, Dan Bikel, Lukas Blecher, Cristian Canton Ferrer, Moya Chen, Guillem Cucurull, David Esiobu, Jude Fernandes, Jeremy Fu, Wenyin Fu, Brian Fuller, Cynthia Gao, Vedanuj Goswami, Naman Goyal, Anthony Hartshorn, Saghar Hosseini, Rui Hou, Hakan Inan, Marcin Kardas, Viktor Kerkez Madian Khabsa, Isabel Kloumann, Artem Korenev, Punit Singh Koura, Marie-Anne Lachaux, Thibaut Lavril, Jenya Lee, Diana Liskovich, Yinghai Lu, Yuning Mao, Xavier Martinet, Todor Mihaylov, Pushkar Mishra, Igor Molybog, Yixin Nie, Andrew Poulton, Jeremy Reizenstein, Rashi Rungta, Kalyan Saladi, Alan Schelten, Ruan Silva, Eric Michael Smith, Ranjan Subramanian, Xiaoqing EllenTan, Binh Tang, Ross Taylor, Adina Williams, Jian Xiang Kuan, Puxin Xu, Zheng Yan, Iliyan Zarov, Yuchen Zhang, Angela Fan, Melanie Kambadur, Sharan Narang, Aurelien Rodriguez, Robert Stojnic, Sergey Edunov, Thomas Scialom의 논문 [LLaMA: Open Foundation and Fine-Tuned Chat Models](https://ai.meta.com/research/publications/llama-2-open-foundation-and-fine-tuned-chat-models/)에서 제안되었습니다. 채팅 어플리케이션에 맞게 미세 조정된 체크포인트를 포함된 7B에서 70B 범위의 매개변수를 가진 기초 언어 모델 모음입니다!
+
+논문의 초록은 다음과 같습니다:
+
+*이 연구에서 우리는 70억에서 700억 파라미터의 범위에서 사전 훈련 및 미세 조정된 대규모 언어 모델(LLMs)의 모음인 Llama 2를 개발 및 공개합니다. Llama 2-Chat라고 불리는 미세 조정된 LLMs은 대화 사용 사례에 최적화되었습니다. 우리의 모델은 테스트한 대부분의 벤치마크에서 오픈 소스 채팅 모델보다 성능이 뛰어나며, 유용성과 안전성에 대한 인적 평가를 바탕으로 비공개 소스 모델을 대체할 수 있는 적절한 대안이 될 수 있습니다. 우리는 Llama 2-Chat의 미세 조정 및 안전성 향상의 접근 방식에 대한 자세한 설명을 제공하여 커뮤니티가 우리의 작업을 기반으로 LLMs의 책임있는 개발에 기여할 수 있도록 합니다.*
+
+[여기](https://huggingface.co/models?search=llama2)에서 모든 Llama2 모델을 확인할 수 있습니다.
+
+
+
+`Llama2` 모델은 `bfloat16`을 사용하여 훈련되었지만, 원래 추론은 `float16`을 사용합니다. 허브에 업로드된 체크포인트는 `torch_dtype = 'float16'`을 사용하며, 이는 `AutoModel` API에 의해 체크포인트를 `torch.float32`에서 `torch.float16`으로 캐스팅하는 데 사용됩니다.
+
+온라인 가중치의 `dtype`은 `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`를 사용하여 모델을 초기화할 때 `torch_dtype="auto"`를 사용하지 않는 한 대부분 관련이 없습니다. 그 이유는 모델이 먼저 다운로드될 것이고 (온라인 체크포인트의 `dtype`을 사용하여) 그다음에 기본 `dtype`인 `torch`로 캐스팅하고(`torch.float32`가 됨), 마지막으로 구성(configuration)에서 제공된 `torch_dtype`이 있는 경우 이를 사용하기 때문입니다.
+
+모델을 `float16`에서 훈련하는 것은 권장되지 않으며 `nan`을 생성하는 것으로 알려져 있습니다. 따라서 모델은 `bfloat16`에서 훈련되어야 합니다.
+
+
+
+🍯 팁:
+
+- Llama2 모델의 가중치는 [이 양식](https://ai.meta.com/resources/models-and-libraries/llama-downloads/)을 작성하여 얻을 수 있습니다.
+- 아키텍처는 처음 버전의 Llama와 매우 유사하며, [이 논문](https://arxiv.org/pdf/2305.13245.pdf)의 내용에 따라 Grouped Query Attention (GQA)이 추가되었습니다.
+- `config.pretraining_tp`를 1과 다른 값으로 설정하면 더 정확하지만 느린 선형 레이어 계산이 활성화되어 원본 로짓과 더 잘 일치하게 됩니다.
+- 원래 모델은 `pad_id = -1`을 사용하는데, 이는 패딩 토큰이 없음을 의미합니다. 동일한 로직을 사용할 수 없으므로 `tokenizer.add_special_tokens({"pad_token":""})`를 사용하여 패딩 토큰을 추가하고 이에 따라 토큰 임베딩 크기를 조정해야 합니다. 또한 `model.config.pad_token_id`를 설정해야 합니다. 모델의 `embed_tokens` 레이어는 `self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.config.padding_idx)`로 초기화되어, 패딩 토큰 인코딩이 0을 출력하도록 합니다. 따라서 초기화 시에 전달하는 것을 권장합니다.
+- 양식을 작성하고 모델 체크포인트 접근 권한을 얻은 후에는 이미 변환된 체크포인트를 사용할 수 있습니다. 그렇지 않고 자신의 모델을 직접 변환하려는 경우, [변환 스크립트](https://github.com/huggingface/transformers/blob/main/src/transformers/models/llama/convert_llama_weights_to_hf.py)를 자유롭게 사용하세요. 스크립트는 다음과 같은 예시의 명령어로 호출할 수 있습니다:
+
+```bash
+python src/transformers/models/llama/convert_llama_weights_to_hf.py \
+ --input_dir /path/to/downloaded/llama/weights --model_size 7B --output_dir /output/path
+```
+
+- 변환 후 모델과 토크나이저는 다음과 같이 로드할 수 있습니다:
+
+```python
+from transformers import LlamaForCausalLM, LlamaTokenizer
+
+tokenizer = LlamaTokenizer.from_pretrained("/output/path")
+model = LlamaForCausalLM.from_pretrained("/output/path")
+```
+
+스크립트를 실행하려면 모델을 float16 정밀도로 전부 호스트할 수 있을 만큼 충분한 CPU RAM이 필요합니다 (가장 큰 버전이 여러 체크포인트로 제공되더라도 각 체크포인트는 모델 가중치의 일부만을 포함하므로 모두 RAM에 로드해야 합니다). 75B 모델의 경우, 총 145GB의 RAM이 필요합니다.
+
+- LLaMA 토크나이저는 [sentencepiece](https://github.com/google/sentencepiece)를 기반으로 한 BPE 모델입니다. sentencepiece의 특징 중 하나는 시퀀스를 디코딩할 때 첫 번째 토큰이 단어의 시작이면 (예: "Banana") 토크나이저는 문자열 앞에 접두사 공간을 추가하지 않는 것입니다.
+
+이 모델은 [Arthur Zucker](https://huggingface.co/ArthurZ)가 [Lysandre Debut](https://huggingface.co/lysandre)의 도움을 받아 제공하였습니다. Hugging Face에서의 구현 코드는 [여기](https://github.com/EleutherAI/gpt-neox)의 GPT-NeoX 를 기반으로 합니다. 저자의 원래 코드는 [여기](https://github.com/facebookresearch/llama)에서 찾을 수 있습니다.
+
+## 리소스 [[resources]]
+
+LLaMA2를 시작하는 데 도움이 될 Hugging Face의 공식 및 커뮤니티(🌎로 표시) 리소스 목록입니다. 여기에 새로운 리소스를 추가하기 위해서 Pull Request를 열어 주시면 검토하겠습니다! 리소스는 기존 리소스와 중복되지 않는 새로운 것을 보여주는 것이 이상적입니다.
+
+- [Llama 2 is here - get it on Hugging Face](https://huggingface.co/blog/llama2), Llama 2에 관한 블로그 포스트와 🤗 Transformers 및 🤗 PEFT와 함께 사용하는 방법에 대한 내용입니다.
+- [LLaMA 2 - Every Resource you need](https://www.philschmid.de/llama-2), LLaMA 2에 대해 알아보고 빠르게 시작하는 데 필요한 관련 리소스의 모음입니다.
+
+
+
+- Google Colab에서 QLoRA와 4-bit 정밀도를 사용하여 Llama 2를 미세 조정하는 방법에 대한 [노트북](https://colab.research.google.com/drive/1PEQyJO1-f6j0S_XJ8DV50NkpzasXkrzd?usp=sharing)입니다. 🌎
+- "Llama-v2-7b-guanaco" 모델을 4-bit QLoRA로 미세 조정하고 PDF에서 Q&A 데이터셋을 생성하는 방법에 대한 [노트북](https://colab.research.google.com/drive/134o_cXcMe_lsvl15ZE_4Y75Kstepsntu?usp=sharing)입니다. 🌎
+
+⚗️ 최적화
+- [Llama 2를 DPO로 미세 조정하기](https://huggingface.co/blog/dpo-trl), TRL 라이브러리의 DPO 방법을 사용하여 특정 데이터셋에서 Llama 2를 미세 조정하는 방법을 안내하는 가이드입니다.
+- [확장 가이드: Llama 2 명령어 조정](https://www.philschmid.de/instruction-tune-llama-2), 입력에서 명령어를 생성하도록 Llama 2를 훈련시키는 방법을 안내하는 가이드로, 명령어를 따르는 모델에서 명령어를 주는 모델로 변환합니다.
+- 개인 컴퓨터에서 QLoRA와 TRL을 사용하여 Llama 2 모델을 미세 조정하는 방법에 대한 [노트북](https://colab.research.google.com/drive/1SYpgFpcmtIUzdE7pxqknrM4ArCASfkFQ?usp=sharing)입니다. 🌎
+
+⚡️ 추론
+- AutoGPTQ 라이브러리의 GPTQ를 사용하여 Llama 2 모델을 양자화하는 방법에 대한 [노트북](https://colab.research.google.com/drive/1TC56ArKerXUpbgRy5vM3woRsbTEVNq7h?usp=sharing)입니다. 🌎
+- 로컬 컴퓨터나 Google Colab에서 4-bit 양자화로 Llama 2 채팅 모델을 실행하는 방법에 대한 [노트북](https://colab.research.google.com/drive/1X1z9Q6domMKl2CnEM0QGHNwidLfR4dW2?usp=sharing)입니다. 🌎
+
+🚀 배포
+- [Amazon SageMaker에서 LLaMA 2 (7-70B) 미세 조정하기](https://www.philschmid.de/sagemaker-llama2-qlora), Amazon SageMaker에서 QLoRA 미세 조정 및 배포에 이르기까지의 완전한 가이드입니다.
+- [Amazon SageMaker에서 Llama 2 7B/13B/70B 배포하기](https://www.philschmid.de/sagemaker-llama-llm), 안전하고 확장 가능한 배포를 위해 Hugging Face의 LLM DLC 컨테이너를 사용하는 방법에 대한 가이드입니다.
+
+
+## LlamaConfig [[llamaconfig]]
+
+[[autodoc]] LlamaConfig
+
+
+## LlamaTokenizer [[llamatokenizer]]
+
+[[autodoc]] LlamaTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## LlamaTokenizerFast [[llamatokenizerfast]]
+
+[[autodoc]] LlamaTokenizerFast
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - update_post_processor
+ - save_vocabulary
+
+## LlamaModel [[llamamodel]]
+
+[[autodoc]] LlamaModel
+ - forward
+
+
+## LlamaForCausalLM [[llamaforcausallm]]
+
+[[autodoc]] LlamaForCausalLM
+ - forward
+
+## LlamaForSequenceClassification [[llamaforsequenceclassification]]
+
+[[autodoc]] LlamaForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/llama3.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/llama3.md
new file mode 100644
index 0000000000000000000000000000000000000000..ca819bfcabaf882e54f5f175fdad3732e1e22cd1
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/llama3.md
@@ -0,0 +1,80 @@
+
+
+# Llama3[[llama3]]
+
+```py3
+import transformers
+import torch
+
+model_id = "meta-llama/Meta-Llama-3-8B"
+
+pipeline = transformers.pipeline("text-generation", model=model_id, model_kwargs={"torch_dtype": torch.bfloat16}, device_map="auto")
+pipeline("Hey how are you doing today?")
+```
+
+## 개요[[overview]]
+
+라마3 모델은 Meta AI 팀이 제안한 [메타 라마3 소개: 현재까지 가장 유능한 공개 가능 LLM](https://ai.meta.com/blog/meta-llama-3/)에서 소개되었습니다.
+
+해당 블로그 포스트의 초록입니다:
+
+*오늘, 광범위한 사용을 위해 이용 가능한 라마의 차세대 모델인 메타 라마3의 첫 두 모델을 공유하게 되어 기쁩니다. 이번 출시는 8B와 70B 매개변수를 가진 사전 훈련 및 지시 미세 조정된 언어 모델을 특징으로 하며, 광범위한 사용 사례를 지원할 수 있습니다. 라마의 이 차세대 모델은 다양한 산업 벤치마크에서 최첨단의 성능을 보여주며, 개선된 추론 능력을 포함한 새로운 기능을 제공합니다. 우리는 이것들이 단연코 해당 클래스에서 최고의 오픈 소스 모델이라고 믿습니다. 오랜 개방적 접근 방식을 지지하며, 우리는 라마3를 커뮤니티 기여자들에게 맡기고 있습니다. 애플리케이션에서 개발자 도구, 평가, 추론 최적화 등에 이르기까지 AI 스택 전반에 걸친 다음 혁신의 물결을 촉발하길 희망합니다. 여러분이 무엇을 만들지 기대하며 여러분의 피드백을 고대합니다.*
+
+라마3 모델의 모든 체크포인트는 [이곳](https://huggingface.co/models?search=llama3)에서 확인하세요.
+원본 코드는 [이곳](https://github.com/meta-llama/llama3)에서 확인할 수 있습니다.
+
+## 사용 팁[[usage-tips]]
+
+
+
+`라마3` 모델들은 `bfloat16`를 사용하여 훈련되었지만, 원래의 추론은 `float16`을 사용합니다. Hub에 업로드된 체크포인트들은 `torch_dtype = 'float16'`을 사용하는데, 이는 `AutoModel` API가 체크포인트를 `torch.float32`에서 `torch.float16`으로 변환하는데 이용됩니다.
+
+ `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`를 사용하여 모델을 초기화할 때, 온라인 가중치의 `dtype`는 `torch_dtype="auto"`를 사용하지 않는 한 대부분 무관합니다. 그 이유는 모델이 먼저 다운로드되고(온라인 체크포인트의 `dtype`를 사용), 그 다음 `torch`의 `dtype`으로 변환되어(`torch.float32`가 됨), 마지막으로 config에 `torch_dtype`이 제공된 경우 가중치가 사용되기 때문입니다.
+
+`float16`으로 모델을 훈련하는 것은 권장되지 않으며 `nan`을 생성하는 것으로 알려져 있습니다. 따라서 모든 모델은 `bfloat16`으로 훈련되어야 합니다.
+
+
+
+팁:
+
+- 라마3 모델을 위한 가중치는 [이 폼](https://ai.meta.com/resources/models-and-libraries/llama-downloads/)을 채우면서 얻어져야 합니다.
+- 아키텍처는 라마2와 정확히 같습니다.
+- 토크나이저는 [tiktoken](https://github.com/openai/tiktoken) (sentencepiece 구현에 기반한 라마2 와는 다르게)에 기반한 BPE 모델입니다. tiktoken 기반 토크나이저가 sebtencepiece 기반 방식과 다른점은 입력 토큰이 vocab에 이미 존재할 때 BPE 병합 룰을 무시하고 싱글 토큰으로 토크나이징한다는 점에서 가장 큰 차이를 보입니다. 자세히 말하면 `"hugging"`이 vocab에 존재하고 기존에 병합이 존재하지 않으면, `["hug","ging"]` 처럼 두 토큰으로 더 작은 단위의 단어를 가지는 것이 아니라, 하나의 토큰만을 자동으로 리턴하는 것을 의미합니다.
+- 기본 모델은 패딩 토큰이 없다는 것을 의미하는 `pad_id = -1`을 사용합니다. 같은 로직을 사용할 수 없으니 `tokenizer.add_special_tokens({"pad_token":""})`를 사용하여 토큰을 추가하고 임베딩 크기도 확실히 조정해야 합니다. `model.config.pad_token_id`도 설정이 필요합니다. 모델의 `embed_tokens` 레이어는 `self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.config.padding_idx)`로 초기화되며, 패딩 토큰을 인코딩하는 것이 0(zero)를 출력하게 할 것인지 그래서 초기화가 추천될때 이를 통화시킬 것인지를 정하게 합니다.
+- 원본 체크포인트는 이 [변환 스크립트](https://github.com/huggingface/transformers/blob/main/src/transformers/models/llama/convert_llama_weights_to_hf.py)를 이용해서 변환 가능합니다. 스크립트는 다음 명령어로 호출할 수 있습니다:
+
+ ```bash
+ python src/transformers/models/llama/convert_llama_weights_to_hf.py \
+ --input_dir /path/to/downloaded/llama/weights --model_size 7B --output_dir /output/path --llama_version 3
+ ```
+
+- 변환 후, 모델과 토크나이저는 다음을 통해 로드된다.
+
+ ```python
+ from transformers import AutoModelForCausalLM, AutoTokenizer
+
+ tokenizer = AutoTokenizer.from_pretrained("/output/path")
+ model = AutoModelForCausalLM.from_pretrained("/output/path")
+ ```
+
+ 이 스크립트를 실행시키려면 모델 전체를 float16 정밀도로 호스팅할 수 있는 충분한 메인메모리가 필요하다는 점을 유의하세요. 가장 큰 버전이 여러 체크포인트로 나뉘어 있더라도, 각 체크포인트가 모델의 가중치 일부를 포함하고 있기 때문에 이를 모두 RAM에 로드해야 합니다. 75B 모델을 예로 들면 대략 145GB의 RAM이 필요합니다.
+
+- `attn_implementation="flash_attention_2"`를 통해서 플래시 어텐션2를 사용할 때, `from_pretrained` 클래스 메서드에 `torch_dtype`를 전달하지 말고 자동 혼합 정밀도(Automatic Mixed-Precision) 학습을 사용하세요. `Trainer`를 사용할 때는 단순히 `fp16` 또는 `bf16`을 `True`로 설정하면 됩니다. 그렇지 않으면 반드시 `torch.autocast`를 사용해야 합니다. 플래시 어텐션은 `fp16`과 `bf16` 데이터 유형만 지원하기 때문입니다.
+
+## 자료[[resources]]
+
+[라마2](./llama2) 문서 페이지에서는 이미 수 많은 멋지고 유익한 자료들을 제공하고 있습니다. 이곳에 라마3에 대한 새로운 자료를 더해주실 컨트리뷰터들을 초대합니다! 🤗
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/mamba.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/mamba.md
new file mode 100644
index 0000000000000000000000000000000000000000..404b9b06b41353949a8db18867d4fce4a8fa452e
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/mamba.md
@@ -0,0 +1,105 @@
+
+
+# 맘바[[mamba]]
+
+## 개요[[overview]]
+
+맘바(Mamba) 모델은 Albert Gu, Tri Dao가 제안한 [맘바: 선택적 상태 공간을 이용한 선형 시간 시퀀스 모델링](https://arxiv.org/abs/2312.00752)라는 논문에서 소개 되었습니다.
+
+이 모델은 `state-space-models`을 기반으로 한 새로운 패러다임 아키텍처입니다. 직관적인 이해를 얻고 싶다면 [이곳](https://srush.github.io/annotated-s4/)을 참고 하세요.
+
+해당 논문의 초록입니다:
+
+*현재 딥러닝에서 흥미로운 응용 프로그램을 구동하는 대부분의 기초 모델들은 거의 보편적으로 트랜스포머 아키텍처와 그 핵심 어텐션 모듈을 기반으로 합니다. 선형 어텐션, 게이트된 컨볼루션과 순환 모델, 구조화된 상태 공간 모델(SSM) 등 많은 준이차시간(subquadratic-time) 아키텍처가 긴 시퀀스에 대한 트랜스포머의 계산 비효율성을 해결하기 위해 개발되었지만, 언어와 같은 중요한 양식에서는 어텐션만큼 성능을 내지 못했습니다. 우리는 이러한 모델의 주요 약점이 내용 기반 추론을 수행하지 못한다는 점임을 알고 몇 가지를 개선했습니다. 첫째, SSM 매개변수를 입력의 함수로 만드는 것만으로도 이산 모달리티(discrete modalities)의 약점을 해결할 수 있어, 현재 토큰에 따라 시퀀스 길이 차원을 따라 정보를 선택적으로 전파하거나 잊을 수 있게 합니다. 둘째, 이러한 변경으로 효율적인 컨볼루션을 사용할 수 없게 되었지만, 우리는 순환 모드에서 하드웨어를 인식하는 병렬 알고리즘을 설계했습니다. 우리는 이러한 선택적 SSM을 어텐션이나 MLP 블록도 없는 단순화된 종단간 신경망 아키텍처인 맘바에 통합시켰습니다. 맘바는 빠른 추론(트랜스포머보다 5배 높은 처리량)과 시퀀스 길이에 대한 선형 확장성을 누리며, 백만 길이 시퀀스까지 실제 데이터에서 성능이 향상됩니다. 일반적인 시퀀스 모델 백본으로서 맘바는 언어, 오디오, 유전체학과 같은 여러 양식에서 최첨단 성능을 달성합니다. 언어 모델링에서 우리의 맘바-3B 모델은 같은 크기의 트랜스포머를 능가하고 두 배 크기의 트랜스포머와 맞먹는 성능을 보이며, 사전 훈련과 다운스트림 평가 모두에서 성능을 나타납니다.*
+
+팁:
+
+- 맘바는 고전적인 트랜스포머와 견줄 만한 새로운 `상태 공간 모델` 아키텍처입니다. 이는 구조화된 상태 공간 모델의 발전 선상에 있으며, [플래시어텐션](https://github.com/Dao-AILab/flash-attention)의 정신을 따르는 효율적인 하드웨어 인식 설계와 구현을 특징으로 합니다.
+- 맘바는 `어텐션` 레이어와 동등한 `믹서(mixer)` 레이어를 쌓습니다. `맘바`의 핵심 로직은 `MambaMixer` 클래스에 있습니다.
+- 두 가지 구현이 공존합니다: 하나는 최적화되어 빠른 cuda커널을 사용하고, 다른 하나는 단순하지만 모든 장치에서 실행할 수 있습니다!
+- 현재 구현은 원본 cuda커널을 활용합니다: 맘바를 위한 플래시 어텐션의 역할을 하는 것은 [`mamba-ssm`](https://github.com/state-spaces/mamba)와 [`causal_conv1d`](https://github.com/Dao-AILab/causal-conv1d) 저장소에 호스팅되어 있습니다. 하드웨어가 지원한다면 반드시 설치하세요!
+- cuda 커널을 최적화하는 방향 보다는, 단순하지만 모든 장치에서 실행가능하도록하는 방향인 '단순구현'의 성능을 빠르게 향상시키는 기여를 더 환영하고 있습니다. 🤗
+
+이 모델은 [ArthurZ](https://huggingface.co/ArthurZ)에 의해 기여되었습니다.
+원본 코드는 [이곳](https://github.com/state-spaces/mamba)에서 확인할 수 있습니다.
+
+# 사용
+
+### 간단한 생성 예제
+
+```python
+from transformers import MambaConfig, MambaForCausalLM, AutoTokenizer
+import torch
+
+tokenizer = AutoTokenizer.from_pretrained("state-spaces/mamba-130m-hf")
+model = MambaForCausalLM.from_pretrained("state-spaces/mamba-130m-hf")
+input_ids = tokenizer("Hey how are you doing?", return_tensors= "pt")["input_ids"]
+
+out = model.generate(input_ids, max_new_tokens=10)
+print(tokenizer.batch_decode(out))
+```
+
+### Peft 파인튜닝
+느린 버전은 학습에서 아주 안정적이진 않습니다. 빠른 버전은 `float32`가 필요합니다!
+
+```python
+from datasets import load_dataset
+from trl import SFTTrainer
+from peft import LoraConfig
+from transformers import AutoTokenizer, AutoModelForCausalLM, TrainingArguments
+model_id = "state-spaces/mamba-130m-hf"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id)
+dataset = load_dataset("Abirate/english_quotes", split="train")
+training_args = TrainingArguments(
+ output_dir="./results",
+ num_train_epochs=3,
+ per_device_train_batch_size=4,
+ logging_dir='./logs',
+ logging_steps=10,
+ learning_rate=2e-3
+)
+lora_config = LoraConfig(
+ r=8,
+ target_modules=["x_proj", "embeddings", "in_proj", "out_proj"],
+ task_type="CAUSAL_LM",
+ bias="none"
+)
+trainer = SFTTrainer(
+ model=model,
+ tokenizer=tokenizer,
+ args=training_args,
+ peft_config=lora_config,
+ train_dataset=dataset,
+ dataset_text_field="quote",
+)
+trainer.train()
+```
+
+## MambaConfig
+
+[[autodoc]] MambaConfig
+
+## MambaModel
+
+[[autodoc]] MambaModel
+ - forward
+
+## MambaLMHeadModel
+
+[[autodoc]] MambaForCausalLM
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/mamba2.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/mamba2.md
new file mode 100644
index 0000000000000000000000000000000000000000..b023914bc1276ab99a3aafb693f97b068d055e82
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/mamba2.md
@@ -0,0 +1,111 @@
+
+
+# 맘바2[[mamba-2]]
+
+## 개요[[overview]]
+
+맘바2 모델은 Tri Dao, Albert Gu가 제안한 [트랜스포머는 SSM이다: 구조화된 상태 공간 이중성을 통한 일반화된 모델과 효율적인 알고리즘](https://arxiv.org/abs/2405.21060)라는 논문에서 소개되었습니다. 맘바2는 맘바1과 유사한 상태 공간 모델로, 단순화된 아키텍처에서 더 나은 성능을 보입니다.
+
+해당 논문의 초록입니다:
+
+*트랜스포머는 언어 모델링에서 딥러닝 성공의 주요 아키텍처였지만, 맘바와 같은 상태 공간 모델(SSM)이 최근 소규모 혹은 중간 규모에서 트랜스포머와 대등하거나 더 나은 성능을 보이는 것으로 나타났습니다. 우리는 이러한 모델 계열들이 실제로 매우 밀접하게 연관되어 있음을 파악했습니다. 그리고 구조화된 준분리(semiseparable) 행렬 중 연구가 잘 이루어진 클래스의 다양한 분해를 통해 연결된 SSM과 어텐션 변형 사이의 풍부한 이론적 연결 프레임워크를 개발했습니다. 상태 공간 이중성(SSD) 프레임워크를 통해 맘바1의 선택적 SSM을 개선한 새로운 아키텍처를 설계할 수 있었고, 트랜스포머와 경쟁력을 유지하면서도 속도는 2~8배 더 빠른 성능을 냅니다.*
+
+팁:
+
+이 버전은 맘바2 구현을 지원해야 하며, 특히 Mistral AI의 [Mamba-2 codestral](https://huggingface.co/mistralai/Mamba-Codestral-7B-v0.1)을 지원합니다. 특히, mamba 2 codestral은 8개의 `groups`로 출시되었는데, 이는 어텐션 기반 모델의 KV 헤드 수와 유사하다고 판단 가능합니다.
+
+이 모델은 `torch_forward`와 `cuda_kernels_forward`라는 두 가지 다른 전방 패스를 가집니다. `cuda_kernels_forward`는 환경에서 cuda 커널을 찾으면 이를 사용하며, prefill에서는 더 느립니다. 즉, 높은 CPU 오버헤드로 인해 "웜업 실행"이 필요하기 때문입니다. 관련 내용은 [이곳](https://github.com/state-spaces/mamba/issues/389#issuecomment-2171755306)과 [이곳](https://github.com/state-spaces/mamba/issues/355#issuecomment-2147597457)을 참고하세요.
+
+컴파일 없이는 `torch_forward` 구현이 3~4배 빠릅니다. 또한, 이 모델에는 위치 임베딩이 없지만 `attention_mask`와 배치 생성의 경우 두 곳에서 은닉 상태(hidden state)를 마스킹하는 특정 로직이 있습니다. 관련 내용은 [이곳](https://github.com/state-spaces/mamba/issues/66#issuecomment-1863563829)을 참고하세요.
+
+이로인해 맘바2 커널의 재구현과 함께 배치 생성 및 캐시된 생성에서 약간의 차이가 예상됩니다. 또한 cuda 커널 또는 torch forward가 제공하는 결과가 약간 다를 것으로 예상됩니다. SSM 알고리즘은 텐서 수축에 크게 의존하는데, 이는 matmul과 동등하지만 연산 순서가 약간 다르며, 이로 인해 더 작은 정밀도에서 차이가 더 커집니다.
+
+또 다른 참고사항으로, 패딩 토큰에 해당하는 은닉 상태(hidden state)의 종료는 두 곳에서 이루어지며 주로 왼쪽 패딩으로 테스트되었습니다. 오른쪽 패딩은 노이즈를 전파하므로 만족스러운 결과를 보장하지 않습니다. `tokenizer.padding_side = "left"`를 사용하면 올바른 패딩 방향을 사용할 수 있습니다.
+
+이 모델은 [Molbap](https://huggingface.co/Molbap)이 기여했으며, [Anton Vlasjuk](https://github.com/vasqu)의 큰 도움을 받았습니다.
+원본 코드는 [이곳](https://github.com/state-spaces/mamba)에서 확인할 수 있습니다.
+
+
+# 사용
+
+### 간단한 생성 예:
+```python
+from transformers import Mamba2Config, Mamba2ForCausalLM, AutoTokenizer
+import torch
+model_id = 'mistralai/Mamba-Codestral-7B-v0.1'
+tokenizer = AutoTokenizer.from_pretrained(model_id, revision='refs/pr/9', from_slow=True, legacy=False)
+model = Mamba2ForCausalLM.from_pretrained(model_id, revision='refs/pr/9')
+input_ids = tokenizer("Hey how are you doing?", return_tensors= "pt")["input_ids"]
+
+out = model.generate(input_ids, max_new_tokens=10)
+print(tokenizer.batch_decode(out))
+```
+
+이곳은 미세조정을 위한 초안 스크립트입니다:
+```python
+from trl import SFTTrainer
+from peft import LoraConfig
+from transformers import AutoTokenizer, Mamba2ForCausalLM, TrainingArguments
+model_id = 'mistralai/Mamba-Codestral-7B-v0.1'
+tokenizer = AutoTokenizer.from_pretrained(model_id, revision='refs/pr/9', from_slow=True, legacy=False)
+tokenizer.pad_token = tokenizer.eos_token
+tokenizer.padding_side = "left" #왼쪽 패딩으로 설정
+
+model = Mamba2ForCausalLM.from_pretrained(model_id, revision='refs/pr/9')
+dataset = load_dataset("Abirate/english_quotes", split="train")
+# CUDA 커널없이는, 배치크기 2가 80GB 장치를 하나 차지합니다.
+# 하지만 정확도는 감소합니다.
+# 실험과 시도를 환영합니다!
+training_args = TrainingArguments(
+ output_dir="./results",
+ num_train_epochs=3,
+ per_device_train_batch_size=2,
+ logging_dir='./logs',
+ logging_steps=10,
+ learning_rate=2e-3
+)
+lora_config = LoraConfig(
+ r=8,
+ target_modules=["embeddings", "in_proj", "out_proj"],
+ task_type="CAUSAL_LM",
+ bias="none"
+)
+trainer = SFTTrainer(
+ model=model,
+ tokenizer=tokenizer,
+ args=training_args,
+ peft_config=lora_config,
+ train_dataset=dataset,
+ dataset_text_field="quote",
+)
+trainer.train()
+```
+
+
+## Mamba2Config
+
+[[autodoc]] Mamba2Config
+
+## Mamba2Model
+
+[[autodoc]] Mamba2Model
+ - forward
+
+## Mamba2LMHeadModel
+
+[[autodoc]] Mamba2ForCausalLM
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/marian.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/marian.md
new file mode 100644
index 0000000000000000000000000000000000000000..79a9641401d01e400c42de70d65f2157fefc97fa
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/marian.md
@@ -0,0 +1,217 @@
+
+
+# MarianMT[[MarianMT]]
+
+
+
+## 개요[[Overview]]
+
+BART와 동일한 모델을 사용하는 번역 모델 프레임워크입니다. 번역 결과는 각 모델 카드의 테스트 세트와 유사하지만, 정확히 일치하지는 않을 수 있습니다. 이 모델은 [sshleifer](https://huggingface.co/sshleifer)가 제공했습니다.
+
+
+## 구현 노트[[Implementation Notes]]
+
+- 각 모델은 약 298 MB를 차지하며, 1,000개 이상의 모델이 제공됩니다.
+- 지원되는 언어 쌍 목록은 [여기](https://huggingface.co/Helsinki-NLP)에서 확인할 수 있습니다.
+- 모델들은 [Jörg Tiedemann](https://researchportal.helsinki.fi/en/persons/j%C3%B6rg-tiedemann)에 의해 [Marian](https://marian-nmt.github.io/) C++ 라이브러리를 이용하여 학습되었습니다. 이 라이브러리는 빠른 학습과 번역을 지원합니다.
+- 모든 모델은 6개 레이어로 이루어진 Transformer 기반의 인코더-디코더 구조입니다. 각 모델의 성능은 모델 카드에 기입되어 있습니다.
+- BPE 전처리가 필요한 80개의 OPUS 모델은 지원되지 않습니다.
+- 모델링 코드는 [`BartForConditionalGeneration`]을 기반으로 하며, 일부 수정사항이 반영되어 있습니다:
+
+ - 정적 (사인 함수 기반) 위치 임베딩 사용 (`MarianConfig.static_position_embeddings=True`)
+ - 임베딩 레이어 정규화 생략 (`MarianConfig.normalize_embedding=False`)
+ - 모델은 생성 시 프리픽스로 `pad_token_id` (해당 토큰 임베딩 값은 0)를 사용하여 시작합니다 (Bart는
+ ``를 사용),
+- Marian 모델을 PyTorch로 대량 변환하는 코드는 `convert_marian_to_pytorch.py`에서 찾을 수 있습니다.
+
+
+## 모델 이름 규칙[[Naming]]
+
+- 모든 모델 이름은 `Helsinki-NLP/opus-mt-{src}-{tgt}` 형식을 따릅니다.
+- 모델의 언어 코드 표기는 일관되지 않습니다. 두 자리 코드는 일반적으로 [여기](https://developers.google.com/admin-sdk/directory/v1/languages)에서 찾을 수 있으며, 세 자리 코드는 "언어 코드 {code}"로 구글 검색을 통해 찾습니다.
+- `es_AR`과 같은 형태의 코드는 `code_{region}` 형식을 의미합니다. 여기서의 예시는 아르헨티나의 스페인어를 의미합니다.
+- 모델 변환은 두 단계로 이루어졌습니다. 처음 1,000개 모델은 ISO-639-2 코드를 사용하고, 두 번째 그룹은 ISO-639-5와 ISO-639-2 코드를 조합하여 언어를 식별합니다.
+
+
+## 예시[[Examples]]
+
+- Marian 모델은 라이브러리의 다른 번역 모델들보다 크기가 작아 파인튜닝 실험과 통합 테스트에 유용합니다.
+- [GPU에서 파인튜닝하기](https://github.com/huggingface/transformers/blob/master/examples/legacy/seq2seq/train_distil_marian_enro.sh)
+
+## 다국어 모델 사용법[[Multilingual Models]]
+
+- 모든 모델 이름은`Helsinki-NLP/opus-mt-{src}-{tgt}` 형식을 따릅니다.
+- 다중 언어 출력을 지원하는 모델의 경우, 출력을 원하는 언어의 언어 코드를 `src_text`의 시작 부분에 추가하여 지정해야 합니다.
+- 모델 카드에서 지원되는 언어 코드의 목록을 확인할 수 있습니다! 예를 들어 [opus-mt-en-roa](https://huggingface.co/Helsinki-NLP/opus-mt-en-roa)에서 확인할 수 있습니다.
+- `Helsinki-NLP/opus-mt-roa-en`처럼 소스 측에서만 다국어를 지원하는 모델의 경우, 별도의 언어 코드 지정이 필요하지 않습니다.
+
+[Tatoeba-Challenge 리포지토리](https://github.com/Helsinki-NLP/Tatoeba-Challenge)의 새로운 다국적 모델은 3자리 언어 코드를 사용합니다:
+
+
+```python
+>>> from transformers import MarianMTModel, MarianTokenizer
+
+>>> src_text = [
+... ">>fra<< this is a sentence in english that we want to translate to french",
+... ">>por<< This should go to portuguese",
+... ">>esp<< And this to Spanish",
+... ]
+
+>>> model_name = "Helsinki-NLP/opus-mt-en-roa"
+>>> tokenizer = MarianTokenizer.from_pretrained(model_name)
+>>> print(tokenizer.supported_language_codes)
+['>>zlm_Latn<<', '>>mfe<<', '>>hat<<', '>>pap<<', '>>ast<<', '>>cat<<', '>>ind<<', '>>glg<<', '>>wln<<', '>>spa<<', '>>fra<<', '>>ron<<', '>>por<<', '>>ita<<', '>>oci<<', '>>arg<<', '>>min<<']
+
+>>> model = MarianMTModel.from_pretrained(model_name)
+>>> translated = model.generate(**tokenizer(src_text, return_tensors="pt", padding=True))
+>>> [tokenizer.decode(t, skip_special_tokens=True) for t in translated]
+["c'est une phrase en anglais que nous voulons traduire en français",
+ 'Isto deve ir para o português.',
+ 'Y esto al español']
+```
+
+허브에 있는 모든 사전 학습된 모델을 확인하는 코드입니다:
+
+```python
+from huggingface_hub import list_models
+
+model_list = list_models()
+org = "Helsinki-NLP"
+model_ids = [x.id for x in model_list if x.id.startswith(org)]
+suffix = [x.split("/")[1] for x in model_ids]
+old_style_multi_models = [f"{org}/{s}" for s in suffix if s != s.lower()]
+```
+
+## 구형 다국어 모델[[Old Style Multi-Lingual Models]]
+
+이 모델들은 OPUS-MT-Train 리포지토리의 구형 다국어 모델들입니다. 각 언어 그룹에 포함된 언어들은 다음과 같습니다:
+
+```python no-style
+['Helsinki-NLP/opus-mt-NORTH_EU-NORTH_EU',
+ 'Helsinki-NLP/opus-mt-ROMANCE-en',
+ 'Helsinki-NLP/opus-mt-SCANDINAVIA-SCANDINAVIA',
+ 'Helsinki-NLP/opus-mt-de-ZH',
+ 'Helsinki-NLP/opus-mt-en-CELTIC',
+ 'Helsinki-NLP/opus-mt-en-ROMANCE',
+ 'Helsinki-NLP/opus-mt-es-NORWAY',
+ 'Helsinki-NLP/opus-mt-fi-NORWAY',
+ 'Helsinki-NLP/opus-mt-fi-ZH',
+ 'Helsinki-NLP/opus-mt-fi_nb_no_nn_ru_sv_en-SAMI',
+ 'Helsinki-NLP/opus-mt-sv-NORWAY',
+ 'Helsinki-NLP/opus-mt-sv-ZH']
+GROUP_MEMBERS = {
+ 'ZH': ['cmn', 'cn', 'yue', 'ze_zh', 'zh_cn', 'zh_CN', 'zh_HK', 'zh_tw', 'zh_TW', 'zh_yue', 'zhs', 'zht', 'zh'],
+ 'ROMANCE': ['fr', 'fr_BE', 'fr_CA', 'fr_FR', 'wa', 'frp', 'oc', 'ca', 'rm', 'lld', 'fur', 'lij', 'lmo', 'es', 'es_AR', 'es_CL', 'es_CO', 'es_CR', 'es_DO', 'es_EC', 'es_ES', 'es_GT', 'es_HN', 'es_MX', 'es_NI', 'es_PA', 'es_PE', 'es_PR', 'es_SV', 'es_UY', 'es_VE', 'pt', 'pt_br', 'pt_BR', 'pt_PT', 'gl', 'lad', 'an', 'mwl', 'it', 'it_IT', 'co', 'nap', 'scn', 'vec', 'sc', 'ro', 'la'],
+ 'NORTH_EU': ['de', 'nl', 'fy', 'af', 'da', 'fo', 'is', 'no', 'nb', 'nn', 'sv'],
+ 'SCANDINAVIA': ['da', 'fo', 'is', 'no', 'nb', 'nn', 'sv'],
+ 'SAMI': ['se', 'sma', 'smj', 'smn', 'sms'],
+ 'NORWAY': ['nb_NO', 'nb', 'nn_NO', 'nn', 'nog', 'no_nb', 'no'],
+ 'CELTIC': ['ga', 'cy', 'br', 'gd', 'kw', 'gv']
+}
+```
+
+영어를 여러 로망스 언어로 번역하는 예제입니다. 여기서는 구형 2자리 언어 코드를 사용합니다:
+
+
+```python
+>>> from transformers import MarianMTModel, MarianTokenizer
+
+>>> src_text = [
+... ">>fr<< this is a sentence in english that we want to translate to french",
+... ">>pt<< This should go to portuguese",
+... ">>es<< And this to Spanish",
+... ]
+
+>>> model_name = "Helsinki-NLP/opus-mt-en-ROMANCE"
+>>> tokenizer = MarianTokenizer.from_pretrained(model_name)
+
+>>> model = MarianMTModel.from_pretrained(model_name)
+>>> translated = model.generate(**tokenizer(src_text, return_tensors="pt", padding=True))
+>>> tgt_text = [tokenizer.decode(t, skip_special_tokens=True) for t in translated]
+["c'est une phrase en anglais que nous voulons traduire en français",
+ 'Isto deve ir para o português.',
+ 'Y esto al español']
+```
+
+## 자료[[Resources]]
+
+- [번역 작업 가이드](../tasks/translation)
+- [요약 작업 가이드](../tasks/summarization)
+- [언어 모델링 작업 가이드](../tasks/language_modeling)
+
+## MarianConfig
+
+[[autodoc]] MarianConfig
+
+## MarianTokenizer
+
+[[autodoc]] MarianTokenizer
+ - build_inputs_with_special_tokens
+
+
+
+
+## MarianModel
+
+[[autodoc]] MarianModel
+ - forward
+
+## MarianMTModel
+
+[[autodoc]] MarianMTModel
+ - forward
+
+## MarianForCausalLM
+
+[[autodoc]] MarianForCausalLM
+ - forward
+
+
+
+
+## TFMarianModel
+
+[[autodoc]] TFMarianModel
+ - call
+
+## TFMarianMTModel
+
+[[autodoc]] TFMarianMTModel
+ - call
+
+
+
+
+## FlaxMarianModel
+
+[[autodoc]] FlaxMarianModel
+ - __call__
+
+## FlaxMarianMTModel
+
+[[autodoc]] FlaxMarianMTModel
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/mistral.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/mistral.md
new file mode 100644
index 0000000000000000000000000000000000000000..4c9f2d7a77d4a2fee499e4db14e88f4c122c10e5
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/mistral.md
@@ -0,0 +1,233 @@
+
+
+# Mistral[[mistral]]
+
+## 개요[[overview]]
+
+미스트랄은 Albert Jiang, Alexandre Sablayrolles, Arthur Mensch, Chris Bamford, Devendra Singh Chaplot, Diego de las Casas, Florian Bressand, Gianna Lengyel, Guillaume Lample, Lélio Renard Lavaud, Lucile Saulnier, Marie-Anne Lachaux, Pierre Stock, Teven Le Scao, Thibaut Lavril, Thomas Wang, Timothée Lacroix, William El Sayed가 작성한 [이 블로그 포스트](https://mistral.ai/news/announcing-mistral-7b/)에서 소개되었습니다.
+
+블로그 포스트의 서두는 다음과 같습니다:
+
+*미스트랄 AI팀은 현존하는 언어 모델 중 크기 대비 가장 강력한 미스트랄7B를 출시하게 되어 자랑스럽습니다.*
+
+미스트랄-7B는 [mistral.ai](https://mistral.ai/)에서 출시한 첫 번째 대규모 언어 모델(LLM)입니다.
+
+### 아키텍처 세부사항[[architectural-details]]
+
+미스트랄-7B는 다음과 같은 구조적 특징을 가진 디코더 전용 트랜스포머입니다:
+
+- 슬라이딩 윈도우 어텐션: 8k 컨텍스트 길이와 고정 캐시 크기로 훈련되었으며, 이론상 128K 토큰의 어텐션 범위를 가집니다.
+- GQA(Grouped Query Attention): 더 빠른 추론이 가능하고 더 작은 크기의 캐시를 사용합니다.
+- 바이트 폴백(Byte-fallback) BPE 토크나이저: 문자들이 절대 어휘 목록 외의 토큰으로 매핑되지 않도록 보장합니다.
+
+더 자세한 내용은 [출시 블로그 포스트](https://mistral.ai/news/announcing-mistral-7b/)를 참조하세요.
+
+### 라이선스[[license]]
+
+`미스트랄-7B`는 아파치 2.0 라이선스로 출시되었습니다.
+
+## 사용 팁[[usage-tips]]
+
+미스트랄 AI팀은 다음 3가지 체크포인트를 공개했습니다:
+
+- 기본 모델인 [미스트랄-7B-v0.1](https://huggingface.co/mistralai/Mistral-7B-v0.1)은 인터넷 규모의 데이터에서 다음 토큰을 예측하도록 사전 훈련되었습니다.
+- 지시 조정 모델인 [미스트랄-7B-Instruct-v0.1](https://huggingface.co/mistralai/Mistral-7B-Instruct-v0.1)은 지도 미세 조정(SFT)과 직접 선호도 최적화(DPO)를 사용한 채팅에 최적화된 기본 모델입니다.
+- 개선된 지시 조정 모델인 [미스트랄-7B-Instruct-v0.2](https://huggingface.co/mistralai/Mistral-7B-Instruct-v0.2)는 v1을 개선한 버전입니다.
+
+기본 모델은 다음과 같이 사용할 수 있습니다:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-v0.1", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to("cuda")
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"My favourite condiment is to ..."
+```
+
+지시 조정 모델은 다음과 같이 사용할 수 있습니다:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-Instruct-v0.2", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-Instruct-v0.2")
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to("cuda")
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"Mayonnaise can be made as follows: (...)"
+```
+
+지시 조정 모델은 입력이 올바른 형식으로 준비되도록 [채팅 템플릿](../chat_templating)을 적용해야 합니다.
+
+## 플래시 어텐션을 이용한 미스트랄 속도향상[[speeding-up-mistral-by-using-flash-attention]]
+
+위의 코드 스니펫들은 어떤 최적화 기법도 사용하지 않은 추론 과정을 보여줍니다. 하지만 모델 내부에서 사용되는 어텐션 메커니즘의 더 빠른 구현인 [플래시 어텐션2](../perf_train_gpu_one.md#flash-attention-2)을 활용하면 모델의 속도를 크게 높일 수 있습니다.
+
+먼저, 슬라이딩 윈도우 어텐션 기능을 포함하는 플래시 어텐션2의 최신 버전을 설치해야 합니다.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+하드웨어와 플래시 어텐션2의 호환여부를 확인하세요. 이에 대한 자세한 내용은 [플래시 어텐션 저장소](https://github.com/Dao-AILab/flash-attention)의 공식 문서에서 확인할 수 있습니다. 또한 모델을 반정밀도(예: `torch.float16`)로 불러와야합니다.
+
+플래시 어텐션2를 사용하여 모델을 불러오고 실행하려면 아래 코드 스니펫을 참조하세요:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-v0.1", torch_dtype=torch.float16, attn_implementation="flash_attention_2", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to("cuda")
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"My favourite condiment is to (...)"
+```
+
+### 기대하는 속도 향상[[expected-speedups]]
+
+다음은 `mistralai/Mistral-7B-v0.1` 체크포인트를 사용한 트랜스포머의 기본 구현과 플래시 어텐션2 버전 모델 사이의 순수 추론 시간을 비교한 예상 속도 향상 다이어그램입니다.
+
+
+
+
+
+### 슬라이딩 윈도우 어텐션[[sliding-window-attention]]
+
+현재 구현은 슬라이딩 윈도우 어텐션 메커니즘과 메모리 효율적인 캐시 관리 기능을 지원합니다. 슬라이딩 윈도우 어텐션을 활성화하려면, 슬라이딩 윈도우 어텐션과 호환되는`flash-attn`(`>=2.3.0`)버전을 사용하면 됩니다.
+
+또한 플래시 어텐션2 모델은 더 메모리 효율적인 캐시 슬라이싱 메커니즘을 사용합니다. 미스트랄 모델의 공식 구현에서 권장하는 롤링 캐시 메커니즘을 따라, 캐시 크기를 고정(`self.config.sliding_window`)으로 유지하고, `padding_side="left"`인 경우에만 배치 생성(batch generation)을 지원하며, 현재 토큰의 절대 위치를 사용해 위치 임베딩을 계산합니다.
+
+## 양자화로 미스트랄 크기 줄이기[[shrinking-down-mistral-using-quantization]]
+
+미스트랄 모델은 70억 개의 파라미터를 가지고 있어, 절반의 정밀도(float16)로 약 14GB의 GPU RAM이 필요합니다. 각 파라미터가 2바이트로 저장되기 때문입니다. 하지만 [양자화](../quantization.md)를 사용하면 모델 크기를 줄일 수 있습니다. 모델을 4비트(즉, 파라미터당 반 바이트)로 양자화하면 약 3.5GB의 RAM만 필요합니다.
+
+모델을 양자화하는 것은 `quantization_config`를 모델에 전달하는 것만큼 간단합니다. 아래에서는 BitsAndBytes 양자화를 사용하지만, 다른 양자화 방법은 [이 페이지](../quantization.md)를 참고하세요:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+>>> # specify how to quantize the model
+>>> quantization_config = BitsAndBytesConfig(
+... load_in_4bit=True,
+... bnb_4bit_quant_type="nf4",
+... bnb_4bit_compute_dtype="torch.float16",
+... )
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-Instruct-v0.2", quantization_config=True, device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-Instruct-v0.2")
+
+>>> prompt = "My favourite condiment is"
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to("cuda")
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"The expected output"
+```
+
+이 모델은 [Younes Belkada](https://huggingface.co/ybelkada)와 [Arthur Zucker](https://huggingface.co/ArthurZ)가 기여했습니다.
+원본 코드는 [이곳](https://github.com/mistralai/mistral-src)에서 확인할 수 있습니다.
+
+## 리소스[[resources]]
+
+미스트랄을 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰해 드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+
+
+- 미스트랄-7B의 지도형 미세조정(SFT)을 수행하는 데모 노트북은 [이곳](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/Mistral/Supervised_fine_tuning_(SFT)_of_an_LLM_using_Hugging_Face_tooling.ipynb)에서 확인할 수 있습니다. 🌎
+- 2024년에 Hugging Face 도구를 사용해 LLM을 미세 조정하는 방법에 대한 [블로그 포스트](https://www.philschmid.de/fine-tune-llms-in-2024-with-trl). 🌎
+- Hugging Face의 [정렬(Alignment) 핸드북](https://github.com/huggingface/alignment-handbook)에는 미스트랄-7B를 사용한 지도형 미세 조정(SFT) 및 직접 선호 최적화(DPO)를 수행하기 위한 스크립트와 레시피가 포함되어 있습니다. 여기에는 단일 GPU에서 QLoRa 및 다중 GPU를 사용한 전체 미세 조정을 위한 스크립트가 포함되어 있습니다.
+- [인과적 언어 모델링 작업 가이드](../tasks/language_modeling)
+
+## MistralConfig[[transformers.MistralConfig]]
+
+[[autodoc]] MistralConfig
+
+## MistralModel[[transformers.MistralModel]]
+
+[[autodoc]] MistralModel
+ - forward
+
+## MistralForCausalLM[[transformers.MistralForCausalLM]]
+
+[[autodoc]] MistralForCausalLM
+ - forward
+
+## MistralForSequenceClassification[[transformers.MistralForSequenceClassification]]
+
+[[autodoc]] MistralForSequenceClassification
+ - forward
+
+## MistralForTokenClassification[[transformers.MistralForTokenClassification]]
+
+[[autodoc]] MistralForTokenClassification
+ - forward
+
+## FlaxMistralModel[[transformers.FlaxMistralModel]]
+
+[[autodoc]] FlaxMistralModel
+ - __call__
+
+## FlaxMistralForCausalLM[[transformers.FlaxMistralForCausalLM]]
+
+[[autodoc]] FlaxMistralForCausalLM
+ - __call__
+
+## TFMistralModel[[transformers.TFMistralModel]]
+
+[[autodoc]] TFMistralModel
+ - call
+
+## TFMistralForCausalLM[[transformers.TFMistralForCausalLM]]
+
+[[autodoc]] TFMistralForCausalLM
+ - call
+
+## TFMistralForSequenceClassification[[transformers.TFMistralForSequenceClassification]]
+
+[[autodoc]] TFMistralForSequenceClassification
+ - call
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/openai-gpt.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/openai-gpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..7e8f57c743bf7173e4fd31657abfb0b27b469f83
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/openai-gpt.md
@@ -0,0 +1,149 @@
+
+
+# OpenAI GPT [[openai-gpt]]
+
+
+
+## 개요 [[overview]]
+
+OpenAI GPT 모델은 Alec Radford, Karthik Narasimhan, Tim Salimans, Ilya Sutskever가 작성한 [Improving Language Understanding by Generative Pre-Training](https://s3-us-west-2.amazonaws.com/openai-assets/research-covers/language-unsupervised/language_understanding_paper.pdf) 논문에서 제안되었습니다. 이는 Toronto Book Corpus와 같은 장기 의존성을 가진 대규모 말뭉치를 사용하여 언어 모델링으로 사전 학습된 인과적(단방향) 트랜스포머입니다.
+
+논문의 초록은 다음과 같습니다:
+
+*자연어 이해는 텍스트 함의, 질문 응답, 의미 유사성 평가, 문서 분류와 같은 다양한 작업을 포함합니다. 비록 대규모의 레이블이 없는 텍스트 말뭉치가 풍부하기는 하지만, 이러한 특정 작업에 대한 학습을 위한 레이블된 데이터는 부족하여 판별적으로 학습된 모델이 적절하게 성능을 발휘하기 어렵습니다. 우리는 다양한 레이블이 없는 텍스트 말뭉치에 대한 언어 모델의 생성적 사전 학습을 수행하고, 각 특정 과제에 대한 판별적 미세 조정을 수행함으로써 이러한 과제에서 큰 성과를 달성할 수 있음을 보여줍니다. 이전 접근 방식과 달리, 우리는 모델 아키텍처에 최소한의 변화를 요구하면서 효과적인 전이를 달성하기 위해 미세 조정 중에 과제 인식 입력 변환(task-aware input transformation)을 사용합니다. 우리는 자연어 이해를 위한 다양한 벤치마크에서 우리의 접근 방식의 효과를 입증합니다. 우리의 general task-agnostic 모델은 각 과제에 특별히 설계된 아키텍처를 사용하는 판별적으로 학습된 모델보다 뛰어나며, 연구된 12개 과제 중 9개 부문에서 최첨단 성능(state of the art)을 크게 향상시킵니다.*
+
+[Write With Transformer](https://transformer.huggingface.co/doc/gpt)는 Hugging Face가 만든 웹 애플리케이션으로, 여러 모델의 생성 능력을 보여주며 그 중에는 GPT도 포함되어 있습니다.
+
+이 모델은 [thomwolf](https://huggingface.co/thomwolf)에 의해 기여되었으며, 원본 코드는 [여기](https://github.com/openai/finetune-transformer-lm)에서 확인할 수 있습니다.
+
+## 사용 팁 [[usage-tips]]
+
+- GPT는 절대 위치 임베딩을 사용하는 모델이므로 입력을 일반적으로 왼쪽보다는 오른쪽에 패딩하는 것이 권장됩니다.
+- GPT는 인과 언어 모델링(Causal Language Modeling, CLM) 목표로 학습되었기 때문에 시퀀스에서 다음 토큰을 예측하는 데 강력한 성능을 보여줍니다. 이를 활용하면 *run_generation.py* 예제 스크립트에서 볼 수 있듯이 GPT-2는 구문적으로 일관된 텍스트를 생성할 수 있습니다.
+
+참고:
+
+*OpenAI GPT* 논문의 원래 토큰화 과정을 재현하려면 `ftfy`와 `SpaCy`를 설치해야 합니다:
+
+```bash
+pip install spacy ftfy==4.4.3
+python -m spacy download en
+```
+
+`ftfy`와 `SpaCy`를 설치하지 않으면 [`OpenAIGPTTokenizer`]는 기본적으로 BERT의 `BasicTokenizer`를 사용한 후 Byte-Pair Encoding을 통해 토큰화합니다(대부분의 사용에 문제가 없으니 걱정하지 마세요).
+
+## 리소스 [[resources]]
+
+OpenAI GPT를 시작하는 데 도움이 되는 공식 Hugging Face 및 커뮤니티(🌎 표시) 리소스 목록입니다. 여기에 리소스를 추가하고 싶다면, Pull Request를 열어주시면 검토하겠습니다! 리소스는 기존 리소스를 복제하지 않고 새로운 것을 보여주는 것이 좋습니다.
+
+
+
+- [SetFit을 사용하여 텍스트 분류에서 OpenAI GPT-3을 능가하는 방법](https://www.philschmid.de/getting-started-setfit) 블로그 게시물.
+- 추가 자료: [텍스트 분류 과제 가이드](../tasks/sequence_classification)
+
+
+
+- [Hugging Face와 함께 비영어 GPT-2 모델을 미세 조정하는 방법](https://www.philschmid.de/fine-tune-a-non-english-gpt-2-model-with-huggingface) 블로그.
+- GPT-2와 함께 [Transformers를 사용한 언어 생성의 다양한 디코딩 방법](https://huggingface.co/blog/how-to-generate)에 대한 블로그.
+- [Scratch에서 CodeParrot 🦜을 훈련하는 방법](https://huggingface.co/blog/codeparrot), 대규모 GPT-2 모델에 대한 블로그.
+- GPT-2와 함께 [TensorFlow 및 XLA를 사용한 더 빠른 텍스트 생성](https://huggingface.co/blog/tf-xla-generate)에 대한 블로그.
+- [Megatron-LM으로 언어 모델을 훈련하는 방법](https://huggingface.co/blog/megatron-training)에 대한 블로그.
+- [좋아하는 아티스트의 스타일로 가사를 생성하도록 GPT2를 미세 조정하는 방법](https://colab.research.google.com/github/AlekseyKorshuk/huggingartists/blob/master/huggingartists-demo.ipynb)에 대한 노트북. 🌎
+- [좋아하는 트위터 사용자의 스타일로 트윗을 생성하도록 GPT2를 미세 조정하는 방법](https://colab.research.google.com/github/borisdayma/huggingtweets/blob/master/huggingtweets-demo.ipynb)에 대한 노트북. 🌎
+- 🤗 Hugging Face 코스의 [인과 언어 모델링](https://huggingface.co/course/en/chapter7/6?fw=pt#training-a-causal-language-model-from-scratch) 장.
+- [`OpenAIGPTLMHeadModel`]은 [인과 언어 모델링 예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/language-modeling#gpt-2gpt-and-causal-language-modeling), [텍스트 생성 예제 스크립트](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-generation/run_generation.py) 및 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)에 의해 지원됩니다.
+- [`TFOpenAIGPTLMHeadModel`]은 [인과 언어 모델링 예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/language-modeling#run_clmpy) 및 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)에 의해 지원됩니다.
+- 추가 자료: [인과 언어 모델링 과제 가이드](../tasks/language_modeling)
+
+
+
+- [Byte-Pair Encoding 토큰화](https://huggingface.co/course/en/chapter6/5)에 대한 강의 자료.
+
+## OpenAIGPTConfig [[transformers.OpenAIGPTConfig]]
+
+[[autodoc]] OpenAIGPTConfig
+
+## OpenAIGPTTokenizer [[transformers.OpenAIGPTTokenizer]]
+
+[[autodoc]] OpenAIGPTTokenizer
+ - save_vocabulary
+
+## OpenAIGPTTokenizerFast [[transformers.OpenAIGPTTokenizerFast]]
+
+[[autodoc]] OpenAIGPTTokenizerFast
+
+## OpenAI specific outputs [[transformers.models.openai.modeling_openai.OpenAIGPTDoubleHeadsModelOutput]]
+
+[[autodoc]] models.openai.modeling_openai.OpenAIGPTDoubleHeadsModelOutput
+
+[[autodoc]] models.openai.modeling_tf_openai.TFOpenAIGPTDoubleHeadsModelOutput
+
+
+
+
+## OpenAIGPTModel [[transformers.OpenAIGPTModel]]
+
+[[autodoc]] OpenAIGPTModel
+ - forward
+
+## OpenAIGPTLMHeadModel [[transformers.OpenAIGPTLMHeadModel]]
+
+[[autodoc]] OpenAIGPTLMHeadModel
+ - forward
+
+## OpenAIGPTDoubleHeadsModel [[transformers.OpenAIGPTDoubleHeadsModel]]
+
+[[autodoc]] OpenAIGPTDoubleHeadsModel
+ - forward
+
+## OpenAIGPTForSequenceClassification [[transformers.OpenAIGPTForSequenceClassification]]
+
+[[autodoc]] OpenAIGPTForSequenceClassification
+ - forward
+
+
+
+
+## TFOpenAIGPTModel [[transformers.TFOpenAIGPTModel]]
+
+[[autodoc]] TFOpenAIGPTModel
+ - call
+
+## TFOpenAIGPTLMHeadModel [[transformers.TFOpenAIGPTLMHeadModel]]
+
+[[autodoc]] TFOpenAIGPTLMHeadModel
+ - call
+
+## TFOpenAIGPTDoubleHeadsModel [[transformers.TFOpenAIGPTDoubleHeadsModel]]
+
+[[autodoc]] TFOpenAIGPTDoubleHeadsModel
+ - call
+
+## TFOpenAIGPTForSequenceClassification [[transformers.TFOpenAIGPTForSequenceClassification]]
+
+[[autodoc]] TFOpenAIGPTForSequenceClassification
+ - call
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/paligemma.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/paligemma.md
new file mode 100644
index 0000000000000000000000000000000000000000..9f5b48086855094ed1d0ad9e746c486760c60ef5
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/paligemma.md
@@ -0,0 +1,80 @@
+
+
+# PaliGemma[[paligemma]]
+
+## 개요[[overview]]
+
+PaliGemma 모델은 구글이 제안한 [PaliGemma – Google의 최첨단 오픈 비전 언어 모델](https://huggingface.co/blog/paligemma)에서 소개 되었습니다. PaliGemma는 [SigLIP](siglip) 비전 인코더와 [Gemma](gemma) 언어 인코더로 구성된 3B 규모의 비전-언어 모델로, 두 인코더가 멀티모달 선형 프로젝션으로 연결되어 있습니다. 이 모델은 이미지를 고정된 수의 VIT토큰으로 분할하고 이를 선택적 프롬프트 앞에 추가 하며, 모든 이미지 토큰과 입력 텍스트 토큰에 대해 전체 블록 어텐션을 사용하는 특징을 가지고 있습니다.
+
+PaliGemma는 224x224, 448x448, 896x896의 3가지 해상도로 제공되며, 3개의 기본 모델과 55개의 다양한 작업에 대해 미세 조정된 버전, 그리고 2개의 혼합 모델이 있습니다.
+
+
+
+ PaliGemma 아키텍처 블로그 포스트.
+
+이 모델은 [Molbap](https://huggingface.co/Molbap)에 의해 기여 되었습니다.
+
+## 사용 팁[[usage-tips]]
+
+PaliGemma의 추론은 다음처럼 수행됩니다:
+
+```python
+from transformers import AutoProcessor, PaliGemmaForConditionalGeneration
+
+model_id = "google/paligemma-3b-mix-224"
+model = PaliGemmaForConditionalGeneration.from_pretrained(model_id)
+processor = AutoProcessor.from_pretrained(model_id)
+
+prompt = "What is on the flower?"
+image_file = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg?download=true"
+raw_image = Image.open(requests.get(image_file, stream=True).raw)
+inputs = processor(raw_image, prompt, return_tensors="pt")
+output = model.generate(**inputs, max_new_tokens=20)
+
+print(processor.decode(output[0], skip_special_tokens=True)[len(prompt):])
+```
+
+- PaliGemma는 대화용으로 설계되지 않았으며, 특정 사용 사례에 대해 미세 조정할 때 가장 잘 작동합니다. PaliGemma를 미세 조정할 수 있는 몇 가지 하위 작업에는 이미지 캡셔닝, 시각적 질문 답변(VQA), 오브젝트 디텍션, 참조 표현 분할 및 문서 이해가 포함됩니다.
+- 모델에 필요한 이미지, 텍스트 및 선택적 레이블을 준비하는데 `PaliGemmaProcessor`를 사용할 수 있습니다. PaliGemma 모델을 미세 조정할 때는, 프로세서에 `suffix`인자를 전달하여 다음 처럼 모델의 `labels`를 생성할 수 있습니다:
+
+```python
+prompt = "What is on the flower?"
+answer = "a bee"
+inputs = processor(images=raw_image, text=prompt, suffix=answer, return_tensors="pt")
+```
+
+## 자료[[resources]]
+
+PaliGemma를 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다.여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+- PaliGemma의 모든 기능을 소개하는 블로그 포스트는 [이곳](https://huggingface.co/blog/paligemma)에서 찾을 수 있습니다. 🌎
+- Trainer API를 사용하여 VQA(Visual Question Answering)를 위해 PaliGemma를 미세 조정하는 방법과 추론에 대한 데모 노트북은 [이곳](https://github.com/huggingface/notebooks/tree/main/examples/paligemma)에서 찾을 수 있습니다. 🌎
+- 사용자 정의 데이터셋(영수증 이미지 -> JSON)에 대해 PaliGemma를 미세 조정하는 방법과 추론에 대한 데모 노트북은 [이곳](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/PaliGemma)에서 찾을 수 있습니다. 🌎
+
+## PaliGemmaConfig[[transformers.PaliGemmaConfig]]
+
+[[autodoc]] PaliGemmaConfig
+
+## PaliGemmaProcessor[[transformers.PaliGemmaProcessor]]
+
+[[autodoc]] PaliGemmaProcessor
+
+## PaliGemmaForConditionalGeneration[[transformers.PaliGemmaForConditionalGeneration]]
+
+[[autodoc]] PaliGemmaForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/patchtsmixer.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/patchtsmixer.md
new file mode 100644
index 0000000000000000000000000000000000000000..e1463eb85de3e5aca2623fe038da4b249f9c629c
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/patchtsmixer.md
@@ -0,0 +1,95 @@
+
+
+# PatchTSMixer[[patchtsmixer]]
+
+## 개요[[overview]]
+
+PatchTSMixer 모델은 Vijay Ekambaram, Arindam Jati, Nam Nguyen, Phanwadee Sinthong, Jayant Kalagnanam이 제안한 [TSMixer: 다변량 시계열 예측을 위한 경량 MLP-Mixer 모델](https://arxiv.org/pdf/2306.09364.pdf)이라는 논문에서 소개되었습니다.
+
+
+PatchTSMixer는 MLP-Mixer 아키텍처를 기반으로 한 경량 시계열 모델링 접근법입니다. 허깅페이스 구현에서는 PatchTSMixer의 기능을 제공하여 패치, 채널, 숨겨진 특성 간의 경량 혼합을 쉽게 수행하여 효과적인 다변량 시계열 모델링을 가능하게 합니다. 또한 간단한 게이트 어텐션부터 사용자 정의된 더 복잡한 셀프 어텐션 블록까지 다양한 어텐션 메커니즘을 지원합니다. 이 모델은 사전 훈련될 수 있으며 이후 예측, 분류, 회귀와 같은 다양한 다운스트림 작업에 사용될 수 있습니다.
+
+
+해당 논문의 초록입니다:
+
+*TSMixer는 패치 처리된 시계열의 다변량 예측 및 표현 학습을 위해 설계된 다층 퍼셉트론(MLP) 모듈로만 구성된 경량 신경망 아키텍처입니다. 우리의 모델은 컴퓨터 비전 분야에서 MLP-Mixer 모델의 성공에서 영감을 받았습니다. 우리는 Vision MLP-Mixer를 시계열에 적용하는 데 따르는 과제를 보여주고, 정확도를 향상시키기 위해 경험적으로 검증된 구성 요소들을 도입합니다. 여기에는 계층 구조 및 채널 상관관계와 같은 시계열 특성을 명시적으로 모델링하기 위해 MLP-Mixer 백본에 온라인 조정 헤드를 부착하는 새로운 설계 패러다임이 포함됩니다. 또한 기존 패치 채널 혼합 방법의 일반적인 문제인 노이즈가 있는 채널 상호작용을 효과적으로 처리하고 다양한 데이터셋에 걸쳐 일반화하기 위한 하이브리드 채널 모델링 접근법을 제안합니다. 추가로, 중요한 특성을 우선시하기 위해 백본에 간단한 게이트 주의 메커니즘을 도입합니다. 이러한 경량 구성 요소들을 통합함으로써, 우리는 단순한 MLP 구조의 학습 능력을 크게 향상시켜 최소한의 컴퓨팅 사용으로 복잡한 트랜스포머 모델들을 능가하는 성능을 달성합니다. 더욱이, TSMixer의 모듈식 설계는 감독 학습과 마스크 자기 감독 학습 방법 모두와 호환되어 시계열 기초 모델의 유망한 구성 요소가 됩니다. TSMixer는 예측 작업에서 최첨단 MLP 및 트랜스포머 모델들을 상당한 차이(8-60%)로 능가합니다. 또한 최신의 강력한 Patch-Transformer 모델 벤치마크들을 메모리와 실행 시간을 크게 줄이면서(2-3배) 성능 면에서도 앞섭니다(1-2%).*
+
+이 모델은 [ajati](https://huggingface.co/ajati), [vijaye12](https://huggingface.co/vijaye12),
+[gsinthong](https://huggingface.co/gsinthong), [namctin](https://huggingface.co/namctin),
+[wmgifford](https://huggingface.co/wmgifford), [kashif](https://huggingface.co/kashif)가 기여했습니다.
+
+## 사용 예[[usage-example]]
+
+아래의 코드 스니펫은 PatchTSMixer 모델을 무작위로 초기화하는 방법을 보여줍니다.
+PatchTSMixer 모델은 [Trainer API](../trainer.md)와 호환됩니다.
+
+```python
+
+from transformers import PatchTSMixerConfig, PatchTSMixerForPrediction
+from transformers import Trainer, TrainingArguments,
+
+
+config = PatchTSMixerConfig(context_length = 512, prediction_length = 96)
+model = PatchTSMixerForPrediction(config)
+trainer = Trainer(model=model, args=training_args,
+ train_dataset=train_dataset,
+ eval_dataset=valid_dataset)
+trainer.train()
+results = trainer.evaluate(test_dataset)
+```
+
+## 사용 팁[[usage-tips]]
+
+이 모델은 시계열 분류와 시계열 회귀에도 사용될 수 있습니다. 각각[`PatchTSMixerForTimeSeriesClassification`]와 [`PatchTSMixerForRegression`] 클래스를 참조하세요.
+
+## 자료[[resources]]
+
+- PatchTSMixer를 자세히 설명하는 블로그 포스트는 여기에서 찾을 수 있습니다 [이곳](https://huggingface.co/blog/patchtsmixer). 이 블로그는 Google Colab에서도 열어볼 수 있습니다.
+
+## PatchTSMixerConfig[[transformers.PatchTSMixerConfig]]
+
+[[autodoc]] PatchTSMixerConfig
+
+
+## PatchTSMixerModel[[transformers.PatchTSMixerModel]]
+
+[[autodoc]] PatchTSMixerModel
+ - forward
+
+
+## PatchTSMixerForPrediction[[transformers.PatchTSMixerForPrediction]]
+
+[[autodoc]] PatchTSMixerForPrediction
+ - forward
+
+
+## PatchTSMixerForTimeSeriesClassification[[transformers.PatchTSMixerForTimeSeriesClassification]]
+
+[[autodoc]] PatchTSMixerForTimeSeriesClassification
+ - forward
+
+
+## PatchTSMixerForPretraining[[transformers.PatchTSMixerForPretraining]]
+
+[[autodoc]] PatchTSMixerForPretraining
+ - forward
+
+
+## PatchTSMixerForRegression[[transformers.PatchTSMixerForRegression]]
+
+[[autodoc]] PatchTSMixerForRegression
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/patchtst.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/patchtst.md
new file mode 100644
index 0000000000000000000000000000000000000000..fc9b0eb51e4a427b26f832a30e8d5c007e9a9bb1
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/patchtst.md
@@ -0,0 +1,76 @@
+
+
+# PatchTST[[patchtst]]
+
+## 개요[[overview]]
+
+The PatchTST 모델은 Yuqi Nie, Nam H. Nguyen, Phanwadee Sinthong, Jayant Kalagnanam이 제안한 [시계열 하나가 64개의 단어만큼 가치있다: 트랜스포머를 이용한 장기예측](https://arxiv.org/abs/2211.14730)라는 논문에서 소개되었습니다.
+
+이 모델은 고수준에서 시계열을 주어진 크기의 패치로 벡터화하고, 결과로 나온 벡터 시퀀스를 트랜스포머를 통해 인코딩한 다음 적절한 헤드를 통해 예측 길이의 예측을 출력합니다. 모델은 다음 그림과 같이 도식화됩니다:
+
+
+
+해당 논문의 초록입니다:
+
+*우리는 다변량 시계열 예측과 자기 감독 표현 학습을 위한 효율적인 트랜스포머 기반 모델 설계를 제안합니다. 이는 두 가지 주요 구성 요소를 기반으로 합니다:
+
+(i) 시계열을 하위 시리즈 수준의 패치로 분할하여 트랜스포머의 입력 토큰으로 사용
+(ii) 각 채널이 모든 시리즈에 걸쳐 동일한 임베딩과 트랜스포머 가중치를 공유하는 단일 단변량 시계열을 포함하는 채널 독립성. 패칭 설계는 자연스럽게 세 가지 이점을 가집니다:
+ - 지역적 의미 정보가 임베딩에 유지됩니다;
+ - 동일한 룩백 윈도우에 대해 어텐션 맵의 계산과 메모리 사용량이 제곱으로 감소합니다
+ - 모델이 더 긴 과거를 참조할 수 있습니다.
+ 우리의 채널 독립적 패치 시계열 트랜스포머(PatchTST)는 최신 트랜스포머 기반 모델들과 비교했을 때 장기 예측 정확도를 크게 향상시킬 수 있습니다. 또한 모델을 자기지도 사전 훈련 작업에 적용하여, 대규모 데이터셋에 대한 지도 학습을 능가하는 아주 뛰어난 미세 조정 성능을 달성했습니다. 한 데이터셋에서 마스크된 사전 훈련 표현을 다른 데이터셋으로 전이하는 것도 최고 수준의 예측 정확도(SOTA)를 산출했습니다.*
+
+이 모델은 [namctin](https://huggingface.co/namctin), [gsinthong](https://huggingface.co/gsinthong), [diepi](https://huggingface.co/diepi), [vijaye12](https://huggingface.co/vijaye12), [wmgifford](https://huggingface.co/wmgifford), [kashif](https://huggingface.co/kashif)에 의해 기여 되었습니다. 원본코드는 [이곳](https://github.com/yuqinie98/PatchTST)에서 확인할 수 있습니다.
+
+## 사용 팁[[usage-tips]]
+
+이 모델은 시계열 분류와 시계열 회귀에도 사용될 수 있습니다. 각각 [`PatchTSTForClassification`]와 [`PatchTSTForRegression`] 클래스를 참조하세요.
+
+## 자료[[resources]]
+
+- PatchTST를 자세히 설명하는 블로그 포스트는 [이곳](https://huggingface.co/blog/patchtst)에서 찾을 수 있습니다.
+이 블로그는 Google Colab에서도 열어볼 수 있습니다.
+
+## PatchTSTConfig[[transformers.PatchTSTConfig]]
+
+[[autodoc]] PatchTSTConfig
+
+## PatchTSTModel[[transformers.PatchTSTModel]]
+
+[[autodoc]] PatchTSTModel
+ - forward
+
+## PatchTSTForPrediction[[transformers.PatchTSTForPrediction]]
+
+[[autodoc]] PatchTSTForPrediction
+ - forward
+
+## PatchTSTForClassification[[transformers.PatchTSTForClassification]]
+
+[[autodoc]] PatchTSTForClassification
+ - forward
+
+## PatchTSTForPretraining[[transformers.PatchTSTForPretraining]]
+
+[[autodoc]] PatchTSTForPretraining
+ - forward
+
+## PatchTSTForRegression[[transformers.PatchTSTForRegression]]
+
+[[autodoc]] PatchTSTForRegression
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/rag.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/rag.md
new file mode 100644
index 0000000000000000000000000000000000000000..0ae88cc7ac5e3e08fc85a3619fb59aaef54a86a1
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/rag.md
@@ -0,0 +1,100 @@
+
+
+# RAG(검색 증강 생성) [[rag]]
+
+
+
+## 개요 [[overview]]
+
+검색 증강 생성(Retrieval-augmented generation, "RAG") 모델은 사전 훈련된 밀집 검색(DPR)과 시퀀스-투-시퀀스 모델의 장점을 결합합니다. RAG 모델은 문서를 검색하고, 이를 시퀀스-투-시퀀스 모델에 전달한 다음, 주변화(marginalization)를 통해 출력을 생성합니다. 검색기와 시퀀스-투-시퀀스 모듈은 사전 훈련된 모델로 초기화되며, 함께 미세 조정되어 검색과 생성 모두 다운스트림 작업(모델을 특정 태스크에 적용하는 것)에 적응할 수 있게 합니다.
+
+이 모델은 Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela의 논문 [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://arxiv.org/abs/2005.11401)를 기반으로 합니다.
+
+논문의 초록은 다음과 같습니다.
+
+*대규모 사전 훈련 언어 모델들은 그들의 매개변수에 사실적 지식을 저장하고 있으며, 다운스트림 NLP 작업에 대해 미세 조정될 때 최첨단 결과를 달성합니다. 그러나 지식에 접근하고 정확하게 조작하는 능력은 여전히 제한적이며, 따라서 지식 집약적 작업에서 그들의 성능은 작업별 아키텍처에 비해 뒤떨어집니다. 또한, 그들의 결정에 대한 근거를 제공하고 세계 지식을 업데이트하는 것은 여전히 열린 연구 문제로 남아 있습니다. 명시적 비매개변수 메모리에 대한 미분 가능한 접근 메커니즘을 가진 사전 훈련 모델은 이 문제를 극복할 수 있지만, 지금까지는 추출적 다운스트림 작업에 대해서만 연구되었습니다. 우리는 언어 생성을 위해 사전 훈련된 매개변수 및 비매개변수 메모리를 결합하는 모델인 검색 증강 생성(RAG)에 대한 일반적인 목적의 미세 조정 방법을 탐구합니다. 우리는 매개변수 메모리가 사전 훈련된 시퀀스-투-시퀀스 모델이고 비매개변수 메모리가 사전 훈련된 신경 검색기로 접근되는 위키피디아의 밀집 벡터 인덱스인 RAG 모델을 소개합니다. 우리는 생성된 전체 시퀀스에 걸쳐 동일한 검색된 구절을 조건으로 하는 RAG 공식과 토큰별로 다른 구절을 사용할 수 있는 RAG 공식을 비교합니다. 우리는 광범위한 지식 집약적 NLP 작업에 대해 모델을 미세 조정하고 평가하며, 매개변수 시퀀스-투-시퀀스 모델과 작업별 검색-추출 아키텍처를 능가하여 세 가지 개방형 도메인 QA 작업에서 최첨단 성능을 달성합니다. 언어 생성 작업의 경우, RAG 모델이 최첨단 매개변수 전용 시퀀스-투-시퀀스 기준선보다 더 구체적이고, 다양하며, 사실적인 언어를 생성한다는 것을 발견했습니다.*
+
+이 모델은 [ola13](https://huggingface.co/ola13)에 의해 기여되었습니다.
+
+## 사용 팁 [[usage-tips]]
+
+검색 증강 생성(Retrieval-augmented generation, "RAG") 모델은 사전 훈련된 밀집 검색(DPR)과 시퀀스-투-시퀀스 모델의 강점을 결합합니다. RAG 모델은 문서를 검색하고, 이를 시퀀스-투-시퀀스 모델에 전달한 다음, 주변화(marginalization)를 통해 출력을 생성합니다. 검색기와 시퀀스-투-시퀀스 모듈은 사전 훈련된 모델로 초기화되며, 함께 미세 조정됩니다. 이를 통해 검색과 생성 모두 다운스트림 작업에 적응할 수 있게 됩니다.
+
+## RagConfig [[transformers.RagConfig]]
+
+[[autodoc]] RagConfig
+
+## RagTokenizer [[transformers.RagTokenizer]]
+
+[[autodoc]] RagTokenizer
+
+## Rag specific outputs [[transformers.models.rag.modeling_rag.RetrievAugLMMarginOutput]]
+
+[[autodoc]] models.rag.modeling_rag.RetrievAugLMMarginOutput
+
+[[autodoc]] models.rag.modeling_rag.RetrievAugLMOutput
+
+## RagRetriever [[transformers.RagRetriever]]
+
+[[autodoc]] RagRetriever
+
+
+
+
+## RagModel [[transformers.RagModel]]
+
+[[autodoc]] RagModel
+ - forward
+
+## RagSequenceForGeneration [[transformers.RagSequenceForGeneration]]
+
+[[autodoc]] RagSequenceForGeneration
+ - forward
+ - generate
+
+## RagTokenForGeneration [[transformers.RagTokenForGeneration]]
+
+[[autodoc]] RagTokenForGeneration
+ - forward
+ - generate
+
+
+
+
+## TFRagModel [[transformers.TFRagModel]]
+
+[[autodoc]] TFRagModel
+ - call
+
+## TFRagSequenceForGeneration [[transformers.TFRagSequenceForGeneration]]
+
+[[autodoc]] TFRagSequenceForGeneration
+ - call
+ - generate
+
+## TFRagTokenForGeneration [[transformers.TFRagTokenForGeneration]]
+
+[[autodoc]] TFRagTokenForGeneration
+ - call
+ - generate
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/swin.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/swin.md
new file mode 100644
index 0000000000000000000000000000000000000000..6919d7e9978e07af4938c633cedb22f80667d9a1
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/swin.md
@@ -0,0 +1,95 @@
+
+
+# Swin Transformer [[swin-transformer]]
+
+## 개요 [[overview]]
+
+Swin Transformer는 Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo가 제안한 논문 [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030)에서 소개되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*이 논문은 Swin Transformer라는 새로운 비전 트랜스포머를 소개합니다. 이 모델은 컴퓨터 비전에서 범용 백본(backbone)으로 사용될 수 있습니다. 트랜스포머를 언어에서 비전으로 적용할 때의 어려움은 두 분야 간의 차이에서 비롯되는데, 예를 들어 시각적 객체의 크기가 크게 변동하며, 이미지의 픽셀 해상도가 텍스트의 단어에 비해 매우 높다는 점이 있습니다. 이러한 차이를 해결하기 위해, 우리는 'Shifted Windows'를 이용해 표현을 계산하는 계층적 트랜스포머를 제안합니다. Shifted Windows 방식은 겹치지 않는 로컬 윈도우에서 self-attention 계산을 제한하여 효율성을 높이는 동시에 윈도우 간 연결을 가능하게 합니다. 이 계층적 구조는 다양한 크기의 패턴을 모델링할 수 있는 유연성을 제공하며, 이미지 크기에 비례한 선형 계산 복잡성을 가지고 있습니다. Swin Transformer의 이러한 특징들은 이미지 분류(Imagenet-1K에서 87.3의 top-1 정확도) 및 객체 검출(COCO test-dev에서 58.7의 박스 AP, 51.1의 마스크 AP)과 같은 밀집 예측 작업, 의미적 분할(ADE20K val에서 53.5의 mIoU)과 같은 광범위한 비전 작업에 적합합니다. 이 모델은 COCO에서 이전 최고 성능을 박스 AP에서 +2.7, 마스크 AP에서 +2.6, ADE20K에서 mIoU에서 +3.2를 초과하는 성과를 보여주며, 트랜스포머 기반 모델이 비전 백본으로서의 잠재력을 입증했습니다. 계층적 설계와 Shifted Windows 방식은 순수 MLP 아키텍처에도 유리하게 작용합니다.*
+
+
+
+ Swin Transformer 아키텍처. 원본 논문에서 발췌.
+
+이 모델은 [novice03](https://huggingface.co/novice03)이 기여하였습니다. Tensorflow 버전은 [amyeroberts](https://huggingface.co/amyeroberts)가 기여했습니다. 원본 코드는 [여기](https://github.com/microsoft/Swin-Transformer)에서 확인할 수 있습니다.
+
+## 사용 팁 [[usage-tips]]
+
+- Swin은 입력의 높이와 너비가 `32`로 나누어질 수 있으면 어떤 크기든 지원할 수 있도록 패딩을 추가합니다.
+- Swin은 *백본*으로 사용할 수 있습니다. `output_hidden_states = True`로 설정하면, `hidden_states`와 `reshaped_hidden_states`를 모두 출력합니다. `reshaped_hidden_states`는 `(batch, num_channels, height, width)` 형식을 가지며, 이는 `(batch_size, sequence_length, num_channels)` 형식과 다릅니다.
+
+## 리소스 [[resources]]
+
+Swin Transformer의 사용을 도울 수 있는 Hugging Face 및 커뮤니티(🌎로 표시)의 공식 자료 목록입니다.
+
+
+
+- [`SwinForImageClassification`]은 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb)을 통해 지원됩니다.
+- 관련 자료: [이미지 분류 작업 가이드](../tasks/image_classification)
+
+또한:
+
+- [`SwinForMaskedImageModeling`]은 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining)를 통해 지원됩니다.
+
+새로운 자료를 추가하고 싶으시다면, 언제든지 Pull Request를 열어주세요! 저희가 검토해 드릴게요. 이때, 추가하는 자료는 기존 자료와 중복되지 않고 새로운 내용을 보여주는 자료여야 합니다.
+
+## SwinConfig [[transformers.SwinConfig]]
+
+[[autodoc]] SwinConfig
+
+
+
+
+## SwinModel [[transformers.SwinModel]]
+
+[[autodoc]] SwinModel
+ - forward
+
+## SwinForMaskedImageModeling [[transformers.SwinForMaskedImageModeling]]
+
+[[autodoc]] SwinForMaskedImageModeling
+ - forward
+
+## SwinForImageClassification [[transformers.SwinForImageClassification]]
+
+[[autodoc]] transformers.SwinForImageClassification
+ - forward
+
+
+
+
+## TFSwinModel [[transformers.TFSwinModel]]
+
+[[autodoc]] TFSwinModel
+ - call
+
+## TFSwinForMaskedImageModeling [[transformers.TFSwinForMaskedImageModeling]]
+
+[[autodoc]] TFSwinForMaskedImageModeling
+ - call
+
+## TFSwinForImageClassification [[transformers.TFSwinForImageClassification]]
+
+[[autodoc]] transformers.TFSwinForImageClassification
+ - call
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/swin2sr.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/swin2sr.md
new file mode 100644
index 0000000000000000000000000000000000000000..931298b9593c632790f7c1e12183ed1795051f77
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/swin2sr.md
@@ -0,0 +1,59 @@
+
+
+# Swin2SR [[swin2sr]]
+
+## 개요 [[overview]]
+
+Swin2SR 모델은 Marcos V. Conde, Ui-Jin Choi, Maxime Burchi, Radu Timofte가 제안한 논문 [Swin2SR: SwinV2 Transformer for Compressed Image Super-Resolution and Restoration](https://arxiv.org/abs/2209.11345)에서 소개되었습니다.
+Swin2SR은 [SwinIR](https://github.com/JingyunLiang/SwinIR/) 모델을 개선하고자 [Swin Transformer v2](swinv2) 레이어를 도입함으로써, 훈련 불안정성, 사전 훈련과 미세 조정 간의 해상도 차이, 그리고 데이터 의존성 문제를 완화시킵니다.
+
+논문의 초록은 다음과 같습니다:
+
+*압축은 스트리밍 서비스, 가상 현실, 비디오 게임과 같은 대역폭이 제한된 시스템을 통해 이미지와 영상을 효율적으로 전송하고 저장하는 데 중요한 역할을 합니다. 하지만 압축은 필연적으로 원본 정보의 손실과 아티팩트를 초래하며, 이는 시각적 품질을 심각하게 저하시킬 수 있습니다. 이러한 이유로, 압축된 이미지의 품질 향상은 활발한 연구 주제가 되고 있습니다. 현재 대부분의 최첨단 이미지 복원 방법은 합성곱 신경망을 기반으로 하지만, SwinIR과 같은 트랜스포머 기반 방법들도 이 작업에서 인상적인 성능을 보여주고 있습니다. 이번 논문에서는 Swin Transformer V2를 사용해 SwinIR을 개선하여 이미지 초해상도 작업, 특히 압축된 입력 시나리오에서 성능을 향상시키고자 합니다. 이 방법을 통해 트랜스포머 비전 모델을 훈련할 때 발생하는 주요 문제들, 예를 들어 훈련 불안정성, 사전 훈련과 미세 조정 간 해상도 차이, 그리고 데이터 의존성을 해결할 수 있습니다. 우리는 JPEG 압축 아티팩트 제거, 이미지 초해상도(클래식 및 경량), 그리고 압축된 이미지 초해상도라는 세 가지 대표적인 작업에서 실험을 수행했습니다. 실험 결과, 우리의 방법인 Swin2SR은 SwinIR의 훈련 수렴성과 성능을 향상시킬 수 있으며, "AIM 2022 Challenge on Super-Resolution of Compressed Image and Video"에서 상위 5위 솔루션으로 선정되었습니다.*
+
+
+
+ Swin2SR 아키텍처. 원본 논문에서 발췌.
+
+이 모델은 [nielsr](https://huggingface.co/nielsr)가 기여하였습니다.
+원본 코드는 [여기](https://github.com/mv-lab/swin2sr)에서 확인할 수 있습니다.
+
+## 리소스 [[resources]]
+
+Swin2SR demo notebook은 [여기](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Swin2SR)에서 확인할 수 있습니다.
+
+SwinSR을 활용한 image super-resolution demo space는 [여기](https://huggingface.co/spaces/jjourney1125/swin2sr)에서 확인할 수 있습니다.
+
+## Swin2SRImageProcessor [[transformers.Swin2SRImageProcessor]]
+
+[[autodoc]] Swin2SRImageProcessor
+ - preprocess
+
+## Swin2SRConfig [[transformers.Swin2SRConfig]]
+
+[[autodoc]] Swin2SRConfig
+
+## Swin2SRModel [[transformers.Swin2SRModel]]
+
+[[autodoc]] Swin2SRModel
+ - forward
+
+## Swin2SRForImageSuperResolution [[transformers.Swin2SRForImageSuperResolution]]
+
+[[autodoc]] Swin2SRForImageSuperResolution
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/swinv2.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/swinv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..3bc420a292ad7bfd80791aafa6f4ecb40bdd4242
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/swinv2.md
@@ -0,0 +1,63 @@
+
+
+# Swin Transformer V2 [[swin-transformer-v2]]
+
+## 개요 [[overview]]
+
+Swin Transformer V2는 Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo가 제안한 논문 [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883)에서 소개되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*대규모 NLP 모델들은 언어 작업에서의 성능을 크게 향상하며, 성능이 포화하는 징후를 보이지 않습니다. 또한, 사람과 유사한 few-shot 학습 능력을 보여줍니다. 이 논문은 대규모 모델을 컴퓨터 비전 분야에서 탐구하고자 합니다. 대형 비전 모델을 훈련하고 적용하는 데 있어 세 가지 주요 문제를 다룹니다: 훈련 불안정성, 사전 학습과 파인튜닝 간의 해상도 차이, 그리고 레이블이 달린 데이터에 대한 높은 요구입니다. 세 가지 주요 기법을 제안합니다: 1) 훈련 안정성을 개선하기 위한 residual-post-norm 방법과 cosine attention의 결합; 2) 저해상도 이미지로 사전 학습된 모델을 고해상도 입력으로 전이할 수 있는 log-spaced continuous position bias 방법; 3) 레이블이 달린 방대한 이미지의 필요성을 줄이기 위한 self-supervised 사전 학습 방법인 SimMIM입니다. 이러한 기법들을 통해 30억 개의 파라미터를 가진 Swin Transformer V2 모델을 성공적으로 훈련하였으며, 이는 현재까지 가장 크고 고밀도의 비전 모델로, 최대 1,536×1,536 해상도의 이미지를 다룰 수 있습니다. 이 모델은 ImageNet-V2 이미지 분류, COCO 객체 탐지, ADE20K 의미론적 분할, Kinetics-400 비디오 행동 분류 등 네 가지 대표적인 비전 작업에서 새로운 성능 기록을 세웠습니다. 또한, 우리의 훈련은 Google의 billion-level 비전 모델과 비교해 40배 적은 레이블이 달린 데이터와 40배 적은 훈련 시간으로 이루어졌다는 점에서 훨씬 더 효율적입니다.*
+
+이 모델은 [nandwalritik](https://huggingface.co/nandwalritik)이 기여하였습니다.
+원본 코드는 [여기](https://github.com/microsoft/Swin-Transformer)에서 확인할 수 있습니다.
+
+## 리소스 [[resources]]
+
+Swin Transformer v2의 사용을 도울 수 있는 Hugging Face 및 커뮤니티(🌎로 표시)의 공식 자료 목록입니다.
+
+
+
+
+- [`Swinv2ForImageClassification`]은 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification)와 [노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb)을 통해 지원됩니다.
+- 관련 자료: [이미지 분류 작업 가이드](../tasks/image_classification)
+
+또한:
+
+- [`Swinv2ForMaskedImageModeling`]는 이 [예제 스크립트](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining)를 통해 지원됩니다.
+
+새로운 자료를 추가하고 싶으시다면, 언제든지 Pull Request를 열어주세요! 저희가 검토해 드릴게요. 이때, 추가하는 자료는 기존 자료와 중복되지 않고 새로운 내용을 보여주는 자료여야 합니다.
+
+## Swinv2Config [[transformers.Swinv2Config]]
+
+[[autodoc]] Swinv2Config
+
+## Swinv2Model [[transformers.Swinv2Model]]
+
+[[autodoc]] Swinv2Model
+ - forward
+
+## Swinv2ForMaskedImageModeling [[transformers.Swinv2ForMaskedImageModeling]]
+
+[[autodoc]] Swinv2ForMaskedImageModeling
+ - forward
+
+## Swinv2ForImageClassification [[transformers.Swinv2ForImageClassification]]
+
+[[autodoc]] transformers.Swinv2ForImageClassification
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/time_series_transformer.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/time_series_transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..2473b0e143b7500ab13d911a34ab406f6f3d0906
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/time_series_transformer.md
@@ -0,0 +1,62 @@
+
+
+# 시계열 트랜스포머[[time-series-transformer]]
+
+## 개요[[overview]]
+
+이 시계열 트랜스포머 모델은 시계열 예측을 위한 기본적인 인코더-디코더 구조의 트랜스포머 입니다.
+이 모델은 [kashif](https://huggingface.co/kashif)에 의해 기여되었습니다.
+
+## 사용 팁[[usage-tips]]
+
+- 다른 라이브러리의 모델들과 마찬가지로, [`TimeSeriesTransformerModel`]은 상단에 헤드가 없는 기본적인 트랜스포머 입니다. [`TimeSeriesTransformerForPrediction`]은 상단에 분포 헤드를 추가하여 시계열 예측에 사용할 수 있습니다. 이 모델은 이른바 확률적 예측 모델이며, 포인트 예측 모델이 아닙니다. 즉 샘플링할 수 있는 분포를 학습하며, 값을 직접 출력 하지는 않습니다.
+- [`TimeSeriesTransformerForPrediction`]은 두개의 블록으로 구성되어 있습니다. 인코더는 `context_length`의 시계열 값을 입력(`past_values`라고 부름)으로 받아들이며, 디코더는 미래의 `prediction_length`만큼 시계열 값을 예측합니다(`future_values`라고 부름). 학습중에는 모델에 `past_values` 와 `future_values`쌍을 모델에 제공해야 합니다.
+- 가공하지 않은 `past_values` 와 `future_values` 쌍 외에도, 일반적으로 모델에 추가적인 특징을 제공합니다. 다음은 그 특징들에 대해 소개합니다:
+ - `past_time_features`: 모델이 `past_values`에 추가할 시간적 특성. 이는 트랜스포머 인코더의 "위치 인코딩" 역할을 합니다.
+ 예를 들어 "월의 일", "연도의 월" 등을 스칼라 값으로 (그리고 벡터로 쌓아서) 나타냅니다.
+ 예시: 특정 시계열 값이 8월 11일에 기록되었다면, [11, 8]을 시간 특성 벡터로 사용할 수 있습니다 (11은 "월의 일", 8은 "연도의 월").
+ - `future_time_features`: 모델이 `future_values`에 추가할 시간적 특성. 이는 트랜스포머 디코더의 "위치 인코딩" 역할을 합니다.
+ 예를 들어 "월의 일", "연도의 월" 등을 스칼라 값으로 (그리고 벡터로 쌓아서) 나타냅니다.
+ 예: 특정 시계열 값이 8월 11일에 얻어졌다면, [11, 8]을 시간 특성 벡터로 사용할 수 있습니다 (11은 "월의 일", 8은 "연도의 월").
+ - `static_categorical_features`: 시간에 따라 변하지 않는 범주형 특성 (즉, 모든 `past_values`와 `future_values`에 대해 동일한 값을 가짐).
+ 예를 들어 특정 시계열을 식별하는 매장 ID나 지역 ID가 있습니다.
+ 이러한 특성은 모든 데이터 포인트(미래의 데이터 포인트 포함)에 대해 알려져 있어야 합니다.
+ - `static_real_features`: 시간에 따라 변하지 않는 실수값 특성 (즉, 모든 `past_values`와 `future_values`에 대해 동일한 값을 가짐).
+ 예를 들어 시계열 값을 가진 제품의 이미지 표현 (시계열이 신발 판매에 관한 것이라면 "신발" 사진의 [ResNet](resnet) 임베딩 처럼)이 있습니다.
+ 이러한 특성은 모든 데이터 포인트(미래의 데이터 포인트 포함)에 대해 알려져 있어야 합니다.
+- 이 모델은 기계 번역을 위한 트랜스포머 훈련과 유사하게 "교사 강제(teacher-forcing)" 방식으로 훈련됩니다. 즉, 훈련 중에 `future_values`를 디코더의 입력으로 오른쪽으로 한 위치 이동시키고, `past_values`의 마지막 값을 앞에 붙입니다. 각 시간 단계에서 모델은 다음 타겟을 예측해야 합니다. 따라서 훈련 설정은 언어를 위한 GPT 모델과 유사하지만, `decoder_start_token_id` 개념이 없습니다 (우리는 단순히 컨텍스트의 마지막 값을 디코더의 초기 입력으로 사용합니다).
+- 추론 시에는 `past_values`의 최종 값을 디코더의 입력으로 제공합니다. 그 다음, 모델에서 샘플링하여 다음 시간 단계에서의 예측을 만들고, 이를 디코더에 공급하여 다음 예측을 만듭니다 (자기회귀 생성이라고도 함).
+
+## 자료 [[resources]]
+
+시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다. 여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+- HuggingFace 블로그에서 시계열 트랜스포머 포스트를 확인하세요: [🤗 트랜스포머와 확률적 시계열 예측](https://huggingface.co/blog/time-series-transformers)
+
+## TimeSeriesTransformerConfig[[transformers.TimeSeriesTransformerConfig]]
+
+[[autodoc]] TimeSeriesTransformerConfig
+
+## TimeSeriesTransformerModel[[transformers.TimeSeriesTransformerModel]]
+
+[[autodoc]] TimeSeriesTransformerModel
+ - forward
+
+## TimeSeriesTransformerForPrediction[[transformers.TimeSeriesTransformerForPrediction]]
+
+[[autodoc]] TimeSeriesTransformerForPrediction
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/timesformer.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/timesformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..aa75cee447a47fc3e45696c7eea4320425006e0d
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/timesformer.md
@@ -0,0 +1,51 @@
+
+
+# TimeSformer [[timesformer]]
+
+## 개요 [[overview]]
+
+TimeSformer 모델은 Facebook Research에서 제안한 [TimeSformer: Is Space-Time Attention All You Need for Video Understanding?](https://arxiv.org/abs/2102.05095)에서 소개되었습니다. 이 연구는 첫 번째 비디오 Transformer로서, 행동 인식 분야에서 중요한 이정표가 되었습니다. 또한 Transformer 기반의 비디오 이해 및 분류 논문에 많은 영감을 주었습니다.
+
+논문의 초록은 다음과 같습니다.
+
+*우리는 공간과 시간에 걸쳐 셀프 어텐션만을 사용하는 합성곱이 없는(convolution-free) 비디오 분류 방법을 제안합니다. 이 방법은 “TimeSformer”라고 불리며, 표준 Transformer 아키텍처를 비디오에 적용하여 프레임 수준 패치 시퀀스로부터 직접 시공간적 특징을 학습할 수 있게 합니다. 우리의 실험적 연구는 다양한 셀프 어텐션 방식을 비교하며, 시간적 어텐션과 공간적 어텐션을 각각의 블록 내에서 별도로 적용하는 “분할 어텐션” 방식이 고려된 설계 선택 중 가장 우수한 비디오 분류 정확도를 제공한다는 것을 시사합니다. 이 혁신적인 설계에도 불구하고, TimeSformer는 Kinetics-400 및 Kinetics-600을 포함한 여러 행동 인식 벤치마크에서 최첨단 결과를 달성했으며, 현재까지 보고된 가장 높은 정확도를 기록했습니다. 마지막으로, 3D 합성곱 네트워크와 비교했을 때, TimeSformer는 더 빠르게 학습할 수 있으며, 약간의 정확도 저하를 감수하면 테스트 효율성이 크게 향상되고, 1분 이상의 긴 비디오 클립에도 적용할 수 있습니다. 코드와 모델은 다음 링크에서 확인할 수 있습니다: [https URL 링크](https://github.com/facebookresearch/TimeSformer).*
+
+이 모델은 [fcakyon](https://huggingface.co/fcakyon)이 기여하였습니다.
+원본 코드는 [여기](https://github.com/facebookresearch/TimeSformer)에서 확인할 수 있습니다.
+
+## 사용 팁 [[usage-tips]]
+
+다양한 사전 학습된 모델의 변형들이 있습니다. 사용하려는 데이터셋에 맞춰 사전 학습된 모델을 선택해야 합니다. 또한, 모델 크기에 따라 클립당 입력 프레임 수가 달라지므로, 사전 학습된 모델을 선택할 때 이 매개변수를 고려해야 합니다.
+
+
+## 리소스 [[resources]]
+
+- [Video classification task guide](../tasks/video_classification)
+
+## TimesformerConfig [[transformers.TimesformerConfig]]
+
+[[autodoc]] TimesformerConfig
+
+## TimesformerModel [[transformers.TimesformerModel]]
+
+[[autodoc]] TimesformerModel
+ - forward
+
+## TimesformerForVideoClassification [[transformers.TimesformerForVideoClassification]]
+
+[[autodoc]] TimesformerForVideoClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/trajectory_transformer.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/trajectory_transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..ac279eff0441965b20ed6523ac0cf7a653ab20dc
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/trajectory_transformer.md
@@ -0,0 +1,49 @@
+
+
+# 궤적 트랜스포머[[trajectory-transformer]]
+
+
+
+
+이 모델은 유지 보수 모드로만 운영되며, 코드를 변경하는 새로운 PR(Pull Request)은 받지 않습니다.
+이 모델을 실행하는 데 문제가 발생한다면, 이 모델을 지원하는 마지막 버전인 v4.30.0를 다시 설치해 주세요. 다음 명령어를 실행하여 재설치할 수 있습니다: `pip install -U transformers==4.30.0`.
+
+
+
+## 개요[[overview]]
+
+Trajectory Transformer 모델은 Michael Janner, Qiyang Li, Sergey Levine이 제안한 [하나의 커다란 시퀀스 모델링 문제로서의 오프라인 강화학습](https://arxiv.org/abs/2106.02039)라는 논문에서 소개되었습니다.
+
+해당 논문의 초록입니다:
+
+*강화학습(RL)은 일반적으로 마르코프 속성을 활용하여 시간에 따라 문제를 인수분해하면서 정적 정책이나 단일 단계 모델을 추정하는 데 중점을 둡니다. 하지만 우리는 RL을 높은 보상 시퀀스로 이어지는 행동 시퀀스를 생성하는 것을 목표로 하는 일반적인 시퀀스 모델링 문제로 볼 수도 있습니다. 이러한 관점에서, 자연어 처리와 같은 다른 도메인에서 잘 작동하는 고용량 시퀀스 예측 모델이 RL 문제에도 효과적인 해결책을 제공할 수 있는지 고려해 볼 만합니다. 이를 위해 우리는 RL을 시퀀스 모델링의 도구로 어떻게 다룰 수 있는지 탐구하며, 트랜스포머 아키텍처를 사용하여 궤적에 대한 분포를 모델링하고 빔 서치를 계획 알고리즘으로 재활용합니다. RL을 시퀀스 모델링 문제로 프레임화하면 다양한 설계 결정이 단순화되어, 오프라인 RL 알고리즘에서 흔히 볼 수 있는 많은 구성 요소를 제거할 수 있습니다. 우리는 이 접근 방식의 유연성을 장기 동역학 예측, 모방 학습, 목표 조건부 RL, 오프라인 RL에 걸쳐 입증합니다. 더 나아가, 이 접근 방식을 기존의 모델 프리 알고리즘과 결합하여 희소 보상, 장기 과제에서 최신 계획기(planner)를 얻을 수 있음을 보여줍니다.*
+
+이 모델은 [CarlCochet](https://huggingface.co/CarlCochet)에 의해 기여되었습니다.
+원본 코드는 [이곳](https://github.com/jannerm/trajectory-transformer)에서 확인할 수 있습니다.
+
+## 사용 팁[[usage-tips]]
+
+이 트랜스포머는 심층 강화학습에 사용됩니다. 사용하려면 이전의 모든 타임스텝에서의 행동, 상태, 보상으로부터 시퀀스를 생성해야 합니다. 이 모델은 이 모든 요소를 함께 하나의 큰 시퀀스(궤적)로 취급합니다.
+
+## TrajectoryTransformerConfig[[transformers.TrajectoryTransformerConfig]]
+
+[[autodoc]] TrajectoryTransformerConfig
+
+## TrajectoryTransformerModel[[transformers.TrajectoryTransformerModel]]
+
+[[autodoc]] TrajectoryTransformerModel
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/vit.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/vit.md
new file mode 100644
index 0000000000000000000000000000000000000000..5f3eb3342718b14d05a4d908f405eac1c67a33e1
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/vit.md
@@ -0,0 +1,172 @@
+
+
+# Vision Transformer (ViT) [[vision-transformer-vit]]
+
+## 개요 [[overview]]
+
+Vision Transformer (ViT) 모델은 Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby가 제안한 논문 [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929)에서 소개되었습니다. 이는 Transformer 인코더를 ImageNet에서 성공적으로 훈련시킨 첫 번째 논문으로, 기존의 잘 알려진 합성곱 신경망(CNN) 구조와 비교해 매우 우수한 결과를 달성했습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*Transformer 아키텍처는 자연어 처리 작업에서 사실상 표준으로 자리 잡았으나, 컴퓨터 비전 분야에서의 적용은 여전히 제한적입니다. 비전에서 어텐션 메커니즘은 종종 합성곱 신경망(CNN)과 결합하여 사용되거나, 전체 구조를 유지하면서 합성곱 신경망의 특정 구성 요소를 대체하는 데 사용됩니다. 우리는 이러한 CNN 의존성이 필요하지 않으며, 이미지 패치를 순차적으로 입력받는 순수한 Transformer가 이미지 분류 작업에서 매우 우수한 성능을 발휘할 수 있음을 보여줍니다. 대규모 데이터로 사전 학습된 후, ImageNet, CIFAR-100, VTAB 등 다양한 중소형 이미지 인식 벤치마크에 적용하면 Vision Transformer(ViT)는 최신 합성곱 신경망과 비교해 매우 우수한 성능을 발휘하면서도 훈련에 필요한 계산 자원을 상당히 줄일 수 있습니다.*
+
+
+
+ ViT 아키텍처. 원본 논문에서 발췌.
+
+원래의 Vision Transformer에 이어, 여러 후속 연구들이 진행되었습니다:
+
+
+- [DeiT](deit) (Data-efficient Image Transformers) (Facebook AI 개발). DeiT 모델은 distilled vision transformers입니다.
+ DeiT의 저자들은 더 효율적으로 훈련된 ViT 모델도 공개했으며, 이는 [`ViTModel`] 또는 [`ViTForImageClassification`]에 바로 사용할 수 있습니다. 여기에는 3가지 크기로 4개의 변형이 제공됩니다: *facebook/deit-tiny-patch16-224*, *facebook/deit-small-patch16-224*, *facebook/deit-base-patch16-224* and *facebook/deit-base-patch16-384*. 그리고 모델에 이미지를 준비하려면 [`DeiTImageProcessor`]를 사용해야 한다는 점에 유의하십시오.
+
+- [BEiT](beit) (BERT pre-training of Image Transformers) (Microsoft Research 개발). BEiT 모델은 BERT (masked image modeling)에 영감을 받고 VQ-VAE에 기반한 self-supervised 방법을 이용하여 supervised pre-trained vision transformers보다 더 우수한 성능을 보입니다.
+
+- DINO (Vision Transformers의 self-supervised 훈련을 위한 방법) (Facebook AI 개발). DINO 방법으로 훈련된 Vision Transformer는 학습되지 않은 상태에서도 객체를 분할할 수 있는 합성곱 신경망에서는 볼 수 없는 매우 흥미로운 능력을 보여줍니다. DINO 체크포인트는 [hub](https://huggingface.co/models?other=dino)에서 찾을 수 있습니다.
+
+- [MAE](vit_mae) (Masked Autoencoders) (Facebook AI 개발). Vision Transformer를 비대칭 인코더-디코더 아키텍처를 사용하여 마스크된 패치의 높은 비율(75%)에서 픽셀 값을 재구성하도록 사전 학습함으로써, 저자들은 이 간단한 방법이 미세 조정 후 supervised 방식의 사전 학습을 능가한다는 것을 보여주었습니다.
+
+이 모델은 [nielsr](https://huggingface.co/nielsr)에 의해 기여되었습니다. 원본 코드(JAX로 작성됨)은 [여기](https://github.com/google-research/vision_transformer)에서 확인할 수 있습니다.
+
+
+참고로, 우리는 Ross Wightman의 [timm 라이브러리](https://github.com/rwightman/pytorch-image-models)에서 JAX에서 PyTorch로 변환된 가중치를 다시 변환했습니다. 모든 공로는 그에게 돌립니다!
+
+## 사용 팁 [[usage-tips]]
+
+- Transformer 인코더에 이미지를 입력하기 위해, 각 이미지는 고정 크기의 겹치지 않는 패치들로 분할된 후 선형 임베딩됩니다. 전체 이미지를 대표하는 [CLS] 토큰이 추가되어, 분류에 사용할 수 있습니다. 저자들은 또한 절대 위치 임베딩을 추가하여, 결과적으로 생성된 벡터 시퀀스를 표준 Transformer 인코더에 입력합니다.
+- Vision Transformer는 모든 이미지가 동일한 크기(해상도)여야 하므로, [ViTImageProcessor]를 사용하여 이미지를 모델에 맞게 리사이즈(또는 리스케일)하고 정규화할 수 있습니다.
+- 사전 학습이나 미세 조정 시 사용된 패치 해상도와 이미지 해상도는 각 체크포인트의 이름에 반영됩니다. 예를 들어, `google/vit-base-patch16-224`는 패치 해상도가 16x16이고 미세 조정 해상도가 224x224인 기본 크기 아키텍처를 나타냅니다. 모든 체크포인트는 [hub](https://huggingface.co/models?search=vit)에서 확인할 수 있습니다.
+- 사용할 수 있는 체크포인트는 (1) [ImageNet-21k](http://www.image-net.org/) (1,400만 개의 이미지와 21,000개의 클래스)에서만 사전 학습되었거나, 또는 (2) [ImageNet](http://www.image-net.org/challenges/LSVRC/2012/) (ILSVRC 2012, 130만 개의 이미지와 1,000개의 클래스)에서 추가로 미세 조정된 경우입니다.
+- Vision Transformer는 224x224 해상도로 사전 학습되었습니다. 미세 조정 시, 사전 학습보다 더 높은 해상도를 사용하는 것이 유리한 경우가 많습니다 ([(Touvron et al., 2019)](https://arxiv.org/abs/1906.06423), [(Kolesnikovet al., 2020)](https://arxiv.org/abs/1912.11370). 더 높은 해상도로 미세 조정하기 위해, 저자들은 원본 이미지에서의 위치에 따라 사전 학습된 위치 임베딩의 2D 보간(interpolation)을 수행합니다.
+- 최고의 결과는 supervised 방식의 사전 학습에서 얻어졌으며, 이는 NLP에서는 해당되지 않는 경우가 많습니다. 저자들은 마스크된 패치 예측(마스크된 언어 모델링에서 영감을 받은 self-supervised 사전 학습 목표)을 사용한 실험도 수행했습니다. 이 접근 방식으로 더 작은 ViT-B/16 모델은 ImageNet에서 79.9%의 정확도를 달성하였으며, 이는 처음부터 학습한 것보다 2% 개선된 결과이지만, 여전히 supervised 사전 학습보다 4% 낮습니다.
+
+### Scaled Dot Product Attention (SDPA) 사용하기 [[using-scaled-dot-product-attention-sdpa]]
+
+PyTorch는 `torch.nn.functional`의 일부로서 native scaled dot-product attention (SDPA) 연산자를 포함하고 있습니다. 이 함수는 입력 및 사용 중인 하드웨어에 따라 여러 구현 방식을 적용할 수 있습니다.자세한 내용은 [공식 문서](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)나 [GPU 추론](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention) 페이지를 참조하십시오.
+
+SDPA는 `torch>=2.1.1`에서 구현이 가능한 경우 기본적으로 사용되지만, `from_pretrained()`에서 `attn_implementation="sdpa"`로 설정하여 SDPA를 명시적으로 요청할 수도 있습니다.
+
+```
+from transformers import ViTForImageClassification
+model = ViTForImageClassification.from_pretrained("google/vit-base-patch16-224", attn_implementation="sdpa", torch_dtype=torch.float16)
+...
+```
+
+최적의 속도 향상을 위해 모델을 반정밀도(예: `torch.float16` 또는 `torch.bfloat16`)로 로드하는 것을 권장합니다.
+
+로컬 벤치마크(A100-40GB, PyTorch 2.3.0, OS Ubuntu 22.04)에서 `float32`와 `google/vit-base-patch16-224` 모델을 사용한 추론 시, 다음과 같은 속도 향상을 확인했습니다.
+
+| Batch size | Average inference time (ms), eager mode | Average inference time (ms), sdpa model | Speed up, Sdpa / Eager (x) |
+|--------------|-------------------------------------------|-------------------------------------------|------------------------------|
+| 1 | 7 | 6 | 1.17 |
+| 2 | 8 | 6 | 1.33 |
+| 4 | 8 | 6 | 1.33 |
+| 8 | 8 | 6 | 1.33 |
+
+## 리소스 [[resources]]
+
+ViT의 추론 및 커스텀 데이터에 대한 미세 조정과 관련된 데모 노트북은 [여기](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/VisionTransformer)에서 확인할 수 있습니다. Hugging Face에서 공식적으로 제공하는 자료와 커뮤니티(🌎로 표시된) 자료 목록은 ViT를 시작하는 데 도움이 될 것입니다. 이 목록에 포함될 자료를 제출하고 싶다면 Pull Request를 열어 주시면 검토하겠습니다. 새로운 내용을 설명하는 자료가 가장 이상적이며, 기존 자료를 중복하지 않도록 해주십시오.
+
+`ViTForImageClassification` 은 다음에서 지원됩니다:
+
+
+- [Hugging Face Transformers로 ViT를 이미지 분류에 맞게 미세 조정하는 방법](https://huggingface.co/blog/fine-tune-vit)에 대한 블로그 포스트
+- [Hugging Face Transformers와 `Keras`를 사용한 이미지 분류](https://www.philschmid.de/image-classification-huggingface-transformers-keras)에 대한 블로그 포스트
+- [Hugging Face Transformers를 사용한 이미지 분류 미세 조정](https://github.com/huggingface/notebooks/blob/main/examples/image_classification.ipynb)에 대한 노트북
+- [Hugging Face Trainer로 CIFAR-10에서 Vision Transformer 미세 조정](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_the_%F0%9F%A4%97_Trainer.ipynb)에 대한 노트북
+- [PyTorch Lightning으로 CIFAR-10에서 Vision Transformer 미세 조정](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Fine_tuning_the_Vision_Transformer_on_CIFAR_10_with_PyTorch_Lightning.ipynb)에 대한 노트북
+
+⚗️ 최적화
+
+- [Optimum을 사용한 양자화를 통해 Vision Transformer(ViT) 가속](https://www.philschmid.de/optimizing-vision-transformer)에 대한 블로그 포스트
+
+⚡️ 추론
+
+- [Google Brain의 Vision Transformer(ViT) 빠른 데모](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/VisionTransformer/Quick_demo_of_HuggingFace_version_of_Vision_Transformer_inference.ipynb)에 대한 노트북
+
+🚀 배포
+
+- [TF Serving으로 Hugging Face에서 Tensorflow Vision 모델 배포](https://huggingface.co/blog/tf-serving-vision)에 대한 블로그 포스트
+- [Vertex AI에서 Hugging Face ViT 배포](https://huggingface.co/blog/deploy-vertex-ai)에 대한 블로그 포스트
+- [TF Serving을 사용하여 Kubernetes에서 Hugging Face ViT 배포](https://huggingface.co/blog/deploy-tfserving-kubernetes)에 대한 블로그 포스트
+
+## ViTConfig [[transformers.ViTConfig]]
+
+[[autodoc]] ViTConfig
+
+## ViTFeatureExtractor [[transformers.ViTFeatureExtractor]]
+
+[[autodoc]] ViTFeatureExtractor
+ - __call__
+
+## ViTImageProcessor [[transformers.ViTImageProcessor]]
+
+[[autodoc]] ViTImageProcessor
+ - preprocess
+
+## ViTImageProcessorFast [[transformers.ViTImageProcessorFast]]
+
+[[autodoc]] ViTImageProcessorFast
+ - preprocess
+
+
+
+
+## ViTModel [[transformers.ViTModel]]
+
+[[autodoc]] ViTModel
+ - forward
+
+## ViTForMaskedImageModeling [[transformers.ViTForMaskedImageModeling]]
+
+[[autodoc]] ViTForMaskedImageModeling
+ - forward
+
+## ViTForImageClassification [[transformers.ViTForImageClassification]]
+
+[[autodoc]] ViTForImageClassification
+ - forward
+
+
+
+
+## TFViTModel [[transformers.TFViTModel]]
+
+[[autodoc]] TFViTModel
+ - call
+
+## TFViTForImageClassification [[transformers.TFViTForImageClassification]]
+
+[[autodoc]] TFViTForImageClassification
+ - call
+
+
+
+
+## FlaxVitModel [[transformers.FlaxViTModel]]
+
+[[autodoc]] FlaxViTModel
+ - __call__
+
+## FlaxViTForImageClassification [[transformers.FlaxViTForImageClassification]]
+
+[[autodoc]] FlaxViTForImageClassification
+ - __call__
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/vivit.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/vivit.md
new file mode 100644
index 0000000000000000000000000000000000000000..c9eee17cb20afc7e808423a4af02f99ec3fc2db9
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/vivit.md
@@ -0,0 +1,42 @@
+
+
+# Video Vision Transformer (ViViT) [[video-vision-transformer-vivit]]
+
+## 개요 [[overview]]
+
+Vivit 모델은 Anurag Arnab, Mostafa Dehghani, Georg Heigold, Chen Sun, Mario Lučić, Cordelia Schmid가 제안한 논문 [ViViT: A Video Vision Transformer](https://arxiv.org/abs/2103.15691)에서 소개되었습니다. 이 논문은 비디오 이해를 위한 pure-transformer 기반의 모델 집합 중에서 최초로 성공한 모델 중 하나를 소개합니다.
+
+논문의 초록은 다음과 같습니다:
+
+*우리는 이미지 분류에서 최근 성공을 거둔 순수 트랜스포머 기반 모델을 바탕으로 비디오 분류를 위한 모델을 제안합니다. 본 모델은 입력 비디오로부터 시공간 토큰을 추출한 후, 이를 일련의 트랜스포머 레이어로 인코딩합니다. 비디오에서 발생하는 긴 토큰 시퀀스를 처리하기 위해, 입력의 공간 및 시간 차원을 분리하는 여러 효율적인 모델 변형을 제안합니다. 트랜스포머 기반 모델은 대규모 학습 데이터셋에서만 효과적이라는 것이 일반적이지만, 우리는 학습 중 모델을 효과적으로 정규화하고, 사전 학습된 이미지 모델을 활용함으로써 상대적으로 작은 데이터셋에서도 학습할 수 있는 방법을 보여줍니다. 또한, 철저한 소거(ablation) 연구를 수행하고 Kinetics 400 및 600, Epic Kitchens, Something-Something v2, Moments in Time을 포함한 여러 비디오 분류 벤치마크에서 최첨단 성과를 달성하여, 기존의 3D 합성곱 신경망 기반 방법들을 능가합니다.*
+
+이 모델은 [jegormeister](https://huggingface.co/jegormeister)가 기여하였습니다. 원본 코드(JAX로 작성됨)는 [여기](https://github.com/google-research/scenic/tree/main/scenic/projects/vivit)에서 확인할 수 있습니다.
+
+## VivitConfig [[transformers.VivitConfig]]
+
+[[autodoc]] VivitConfig
+
+## VivitImageProcessor [[transformers.VivitImageProcessor]]
+
+[[autodoc]] VivitImageProcessor
+ - preprocess
+
+## VivitModel [[transformers.VivitModel]]
+
+[[autodoc]] VivitModel
+ - forward
+
+## VivitForVideoClassification [[transformers.VivitForVideoClassification]]
+
+[[autodoc]] transformers.VivitForVideoClassification
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/whisper.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/whisper.md
new file mode 100644
index 0000000000000000000000000000000000000000..f48bae1e60f5d0d7ba7ffe7c69b26bca837f0fa9
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/whisper.md
@@ -0,0 +1,128 @@
+
+
+# Whisper [[whisper]]
+
+## 개요 [[overview]]
+
+Whisper 모델은 Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever에 의해 [Robust Speech Recognition via Large-Scale Weak Supervision](https://cdn.openai.com/papers/whisper.pdf)에서 제안되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*우리는 인터넷에서 대량의 오디오를 글로 옮긴 것을 예측하도록 간단히 훈련된 음성 처리 시스템의 성능을 연구합니다. 68만 시간의 다국어 및 다중 작업 지도(multitask supervision)에 확장했을 때, 결과 모델은 표준 벤치마크에 잘 일반화되며, 미세 조정이 필요 없는 제로샷 전송 설정에서 이전의 완전히 지도된(fully-supervised) 결과와 경쟁할 수 있는 경우가 많습니다. 사람과 비교하면, 이 모델은 사람의 정확도와 견고성에 근접합니다. 우리는 강력한 음성 처리를 위한 추가 작업의 기반이 될 모델과 추론 코드를 공개합니다.*
+
+
+
+팁:
+
+- 이 모델은 일반적으로 별도의 미세 조정 없이도 잘 작동합니다.
+- 아키텍처는 고전적인 인코더-디코더 아키텍처를 따르기 때문에, 추론을 위해 [`~generation.GenerationMixin.generate`] 함수를 사용합니다.
+- 현재 추론은 짧은 형식에만 구현되어 있으며, 오디오는 30초 미만의 세그먼트로 미리 분할되어야 합니다. 타임스탬프를 포함한 긴 형식에 대한 추론은 향후 릴리스에서 구현될 예정입니다.
+- [`WhisperProcessor`]를 사용하여 모델에 사용할 오디오를 준비하고, 예측된 ID를 텍스트로 디코딩할 수 있습니다.
+
+- 모델과 프로세서를 변환하려면 다음을 사용하는 것이 좋습니다:
+
+```bash
+python src/transformers/models/whisper/convert_openai_to_hf.py --checkpoint_path "" --pytorch_dump_folder_path "Arthur/whisper-3" --convert_preprocessor True
+```
+스크립트는 OpenAI 체크포인트에서 필요한 모든 매개변수를 자동으로 결정합니다. OpenAI 변환을 수행하려면 `tiktoken` 라이브러리를 설치해야 합니다.
+라이브러리를 설치해야 OpenAI 토큰화기를 `tokenizers` 버전으로 변환할 수 있습니다.
+
+이 모델은 [Arthur Zucker](https://huggingface.co/ArthurZ)에 의해 제공되었습니다. 이 모델의 Tensorflow 버전은 [amyeroberts](https://huggingface.co/amyeroberts)에 의해 제공되었습니다.
+원본 코드는 [여기](https://github.com/openai/whisper)에서 찾을 수 있습니다.
+
+
+
+## WhisperConfig [[whisperconfig]]
+
+[[autodoc]] WhisperConfig
+
+## WhisperTokenizer [[whispertokenizer]]
+
+[[autodoc]] WhisperTokenizer
+ - set_prefix_tokens
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## WhisperTokenizerFast [[whispertokenizerfast]]
+
+[[autodoc]] WhisperTokenizerFast
+ - set_prefix_tokens
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## WhisperFeatureExtractor [[whisperfeatureextractor]]
+
+[[autodoc]] WhisperFeatureExtractor
+ - __call__
+
+## WhisperProcessor [[whisperprocessor]]
+
+[[autodoc]] WhisperProcessor
+ - __call__
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+
+## WhisperModel [[whispermodel]]
+
+[[autodoc]] WhisperModel
+ - forward
+ - _mask_input_features
+
+## WhisperForConditionalGeneration [[whisperforconditionalgeneration]]
+
+[[autodoc]] WhisperForConditionalGeneration
+ - forward
+
+## WhisperForAudioClassification [[whisperforaudioclassification]]
+
+[[autodoc]] WhisperForAudioClassification
+ - forward
+
+
+
+## TFWhisperModel [[tfwhispermodel]]
+
+[[autodoc]] TFWhisperModel
+ - call
+
+## TFWhisperForConditionalGeneration [[tfwhisperforconditionalgeneration]]
+
+[[autodoc]] TFWhisperForConditionalGeneration
+ - call
+
+
+## FlaxWhisperModel [[flaxwhispermodel]]
+
+[[autodoc]] FlaxWhisperModel
+ - __call__
+
+## FlaxWhisperForConditionalGeneration [[flaxwhisperforconditionalgeneration]]
+
+[[autodoc]] FlaxWhisperForConditionalGeneration
+ - __call__
+
+## FlaxWhisperForAudioClassification [[flaxwhisperforaudioclassification]]
+
+[[autodoc]] FlaxWhisperForAudioClassification
+ - __call__
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_memory_anatomy.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_memory_anatomy.md
new file mode 100644
index 0000000000000000000000000000000000000000..a5c3a0f35292af514fc7ab2efca9f765d6ee7941
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_memory_anatomy.md
@@ -0,0 +1,242 @@
+
+
+# 모델 학습 해부하기 [[model-training-anatomy]]
+
+모델 훈련 속도와 메모리 활용의 효율성을 향상시키기 위해 적용할 수 있는 성능 최적화 기술을 이해하려면 GPU가 훈련 중에 어떻게 활용되는지, 그리고 수행되는 연산에 따라 연산 강도가 어떻게 변하는지에 익숙해져야 합니다.
+
+먼저 GPU 활용과 모델 훈련 실행에 대한 예시를 살펴보겠습니다. 데모를 위해 몇몇 라이브러리를 설치해야 합니다:
+
+```bash
+pip install transformers datasets accelerate nvidia-ml-py3
+```
+
+`nvidia-ml-py3` 라이브러리는 Python 내부에서 모델의 메모리 사용량을 모니터링할 수 있게 해줍니다. 터미널의 `nvidia-smi` 명령어에 익숙할 수 있는데, 이 라이브러리는 Python에서 직접 동일한 정보에 접근할 수 있게 해줍니다.
+
+그 다음, 100과 30000 사이의 무작위 토큰 ID와 분류기를 위한 이진 레이블인 더미 데이터를 생성합니다.
+길이가 각각 512인 총 512개의 시퀀스를 가져와 PyTorch 형식의 [`~datasets.Dataset`]에 저장합니다.
+
+
+```py
+>>> import numpy as np
+>>> from datasets import Dataset
+
+
+>>> seq_len, dataset_size = 512, 512
+>>> dummy_data = {
+... "input_ids": np.random.randint(100, 30000, (dataset_size, seq_len)),
+... "labels": np.random.randint(0, 1, (dataset_size)),
+... }
+>>> ds = Dataset.from_dict(dummy_data)
+>>> ds.set_format("pt")
+```
+
+GPU 활용 및 [`Trainer`]로 실행한 훈련 과정에 대한 요약 통계를 출력하기 위해 두 개의 도우미 함수를 정의하겠습니다:
+
+```py
+>>> from pynvml import *
+
+
+>>> def print_gpu_utilization():
+... nvmlInit()
+... handle = nvmlDeviceGetHandleByIndex(0)
+... info = nvmlDeviceGetMemoryInfo(handle)
+... print(f"GPU memory occupied: {info.used//1024**2} MB.")
+
+
+>>> def print_summary(result):
+... print(f"Time: {result.metrics['train_runtime']:.2f}")
+... print(f"Samples/second: {result.metrics['train_samples_per_second']:.2f}")
+... print_gpu_utilization()
+```
+
+시작할 때 GPU 메모리가 비어 있는지 확인해 봅시다:
+
+```py
+>>> print_gpu_utilization()
+GPU memory occupied: 0 MB.
+```
+
+좋습니다. 모델을 로드하기 전에는 예상대로 GPU 메모리가 점유되지 않았습니다. 그렇지 않다면 사용자의 기기에서 GPU 메모리를 사용하는 모든 프로세스를 중단해야 합니다. 그러나 사용자는 모든 여유 GPU 메모리를 사용할 수는 없습니다. 모델이 GPU에 로드될 때 커널도 로드되므로 1-2GB의 메모리를 차지할 수 있습니다. 얼마나 되는지 확인하기 위해 GPU에 작은 텐서를 로드하여 커널이 로드되도록 트리거합니다.
+
+```py
+>>> import torch
+
+
+>>> torch.ones((1, 1)).to("cuda")
+>>> print_gpu_utilization()
+GPU memory occupied: 1343 MB.
+```
+
+커널만으로도 GPU 메모리의 1.3GB를 차지합니다. 이제 모델이 얼마나 많은 공간을 사용하는지 확인해 보겠습니다.
+
+## 모델 로드 [[load-model]]
+
+우선, `google-bert/bert-large-uncased` 모델을 로드합니다. 모델의 가중치를 직접 GPU에 로드해서 가중치만이 얼마나 많은 공간을 차지하는지 확인할 수 있습니다.
+
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-large-uncased").to("cuda")
+>>> print_gpu_utilization()
+GPU memory occupied: 2631 MB.
+```
+
+모델의 가중치만으로도 GPU 메모리를 1.3 GB 차지하는 것을 볼 수 있습니다. 정확한 숫자는 사용하는 GPU에 따라 다릅니다. 최신 GPU에서는 모델 사용 속도를 높이는 최적화된 방식으로 가중치가 로드되므로, 모델이 더 많은 공간을 차지할 수 있습니다. 이제 `nvidia-smi` CLI와 동일한 결과를 얻는지 빠르게 확인할 수 있습니다:
+
+
+```bash
+nvidia-smi
+```
+
+```bash
+Tue Jan 11 08:58:05 2022
++-----------------------------------------------------------------------------+
+| NVIDIA-SMI 460.91.03 Driver Version: 460.91.03 CUDA Version: 11.2 |
+|-------------------------------+----------------------+----------------------+
+| GPU Name Persistence-M| Bus-Id Disp.A | Volatile Uncorr. ECC |
+| Fan Temp Perf Pwr:Usage/Cap| Memory-Usage | GPU-Util Compute M. |
+| | | MIG M. |
+|===============================+======================+======================|
+| 0 Tesla V100-SXM2... On | 00000000:00:04.0 Off | 0 |
+| N/A 37C P0 39W / 300W | 2631MiB / 16160MiB | 0% Default |
+| | | N/A |
++-------------------------------+----------------------+----------------------+
+
++-----------------------------------------------------------------------------+
+| Processes: |
+| GPU GI CI PID Type Process name GPU Memory |
+| ID ID Usage |
+|=============================================================================|
+| 0 N/A N/A 3721 C ...nvs/codeparrot/bin/python 2629MiB |
++-----------------------------------------------------------------------------+
+```
+
+이전과 동일한 숫자가 출력되고 16GB 메모리를 가진 V100 GPU를 사용하고 있다는 것도 볼 수 있습니다. 그러므로 이제 모델 훈련을 시작하여 GPU 메모리 사용량이 어떻게 달라지는지 볼 수 있습니다. 우선 몇몇 표준 훈련 인수를 설정합니다:
+
+```py
+default_args = {
+ "output_dir": "tmp",
+ "eval_strategy": "steps",
+ "num_train_epochs": 1,
+ "log_level": "error",
+ "report_to": "none",
+}
+```
+
+
+
+여러 실험을 실행할 계획이라면, 실험 간에 메모리를 제대로 비우기 위해서 Python 커널을 실험 사이마다 재시작해야 합니다.
+
+
+
+## 기본 훈련에서의 메모리 활용 [[memory-utilization-at-vanilla-training]]
+
+[`Trainer`]를 사용하여, GPU 성능 최적화 기술을 사용하지 않고 배치 크기가 4인 모델을 훈련시키겠습니다:
+
+```py
+>>> from transformers import TrainingArguments, Trainer, logging
+
+>>> logging.set_verbosity_error()
+
+
+>>> training_args = TrainingArguments(per_device_train_batch_size=4, **default_args)
+>>> trainer = Trainer(model=model, args=training_args, train_dataset=ds)
+>>> result = trainer.train()
+>>> print_summary(result)
+```
+
+```
+Time: 57.82
+Samples/second: 8.86
+GPU memory occupied: 14949 MB.
+```
+
+우리는 비교적 작은 배치 크기로도 전체 GPU 메모리를 거의 다 차지하는 것을 볼 수 있습니다. 그러나 배치 크기가 클수록 모델 수렴 속도가 빨라지고 최종 성능이 향상되는 경우가 많습니다. 그래서 이상적으로는 GPU 제한이 아닌 우리 모델의 요구사항에 맞게 배치 크기를 조정하려고 합니다. 흥미롭게도 우리는 모델의 크기보다 훨씬 더 많은 메모리를 사용합니다. 왜 이런 현상이 발생하는지 조금 더 잘 이해하기 위해 모델의 연산과 메모리 요구 사항을 살펴보겠습니다.
+
+## 모델의 연산 해부하기 [[anatomy-of-models-operations]]
+
+트랜스포머 아키텍처에는 연산 강도(compute-intensity)에 따라 그룹화된 3가지 주요 연산 그룹이 있습니다.
+
+1. **텐서 축약(Tensor Contractions)**
+
+ 선형 레이어와 멀티헤드 어텐션의 구성 요소는 모두 **행렬-행렬 곱셈(matrix-matrix multiplications)**을 일괄적으로 처리합니다. 이 연산은 트랜스포머 훈련에서 가장 연산 강도가 높은 부분입니다.
+
+2. **통계 정규화(Statistical Normalizations)**
+
+ 소프트맥스와 레이어 정규화는 텐서 축약보다 연산 강도가 낮습니다. 하나 이상의 **감소 연산(reduction operations)**을 포함하며, 그 결과는 map을 통해 적용됩니다.
+
+3. **원소별 연산자(Element-wise Operators)**
+
+ 그 외 연산자들, **편향(biases), 드롭아웃(dropout), 활성화 함수(activations), 잔차 연결(residual connections)**이 여기에 해당합니다. 이 연산들은 연산 강도가 가장 낮습니다.
+
+이러한 지식은 성능 병목 현상을 분석할 때 도움이 될 수 있습니다.
+
+이 내용은 [Data Movement Is All You Need: A Case Study on Optimizing Transformers 2020](https://arxiv.org/abs/2007.00072)을 참고하였습니다.
+
+
+## 모델의 메모리 구조 [[anatomy-of-models-memory]]
+
+모델을 훈련시키는 데는 단순히 GPU에 모델을 올리는 것보다 훨씬 더 많은 메모리를 사용한다는 것을 보았습니다. 이는 훈련 중 GPU 메모리를 사용하는 많은 구성 요소가 있기 때문입니다. GPU 메모리의 구성 요소는 다음과 같습니다:
+
+1. 모델 가중치
+2. 옵티마이저 상태
+3. 그라디언트
+4. 그라디언트 계산을 위해 저장된 순방향 활성화
+5. 임시 버퍼
+6. 기능별 메모리
+
+AdamW를 사용하여 혼합 정밀도로 훈련된 일반적인 모델은 모델 파라미터당 18 바이트와 활성화 메모리가 필요합니다. 추론 단계에서는 옵티마이저와 그라디언트가 필요하지 않으므로 이들은 제외합니다. 따라서 혼합 정밀도 추론의 경우 모델 매개변수당 6 바이트와 활성화 메모리가 필요합니다.
+
+자세히 살펴보겠습니다.
+
+**모델 가중치:**
+
+- fp32 훈련의 경우 매개 변수 수 * 4 바이트
+- 혼합 정밀도 훈련의 경우 매개 변수 수 * 6 바이트 (메모리에 fp32와 fp16 두 가지 모델을 유지)
+
+**옵티마이저 상태:**
+
+- 일반 AdamW의 경우 매개 변수 수 * 8 바이트 (2가지 상태 유지)
+- [bitsandbytes](https://github.com/TimDettmers/bitsandbytes)와 같은 8비트 AdamW 옵티마이저의 경우 매개 변수 수 * 2 바이트
+- Momentum을 가진 SGD와 같은 옵티마이저의 경우 매개 변수 수 * 4 바이트 (하나의 상태만 유지)
+
+**그라디언트**
+
+- fp32 또는 혼합 정밀도 훈련의 경우 매개 변수 수 * 4 바이트 (그라디언트는 항상 fp32으로 유지됩니다.)
+
+**순방향 활성화**
+
+- 크기는 여러 요인에 따라 달라지며, 주요 요인은 시퀀스 길이, 은닉 상태의 크기 및 배치 크기입니다.
+
+순방향 및 역방향 함수에서 전달 및 반환되는 입력과 출력이 있으며, 그라디언트 계산을 위해 저장된 순방향 활성화가 있습니다.
+
+**임시 메모리**
+
+더불어 모든 종류의 임시 변수는 연산이 완료되면 곧바로 해제되지만, 그 순간에는 추가 메모리가 필요할 수 있고 OOM을 유발할 수 있습니다. 따라서 코딩할 때 이러한 임시 변수에 대해 전략적으로 생각하고 때로는 더 이상 필요 없는 임시 변수를 즉시 명시적으로 메모리에서 제거하는 것이 중요합니다.
+
+**기능별 메모리**
+
+그런 다음, 소프트웨어에는 특별한 메모리 요구 사항이 있을 수 있습니다. 예를 들어, 빔 검색을 사용하여 텍스트를 생성할 때 소프트웨어는 입력과 출력 사본을 여러 개 유지해야 합니다.
+
+**`forward` vs `backward` 실행 속도**
+
+합성곱과 선형 레이어의 경우 순방향에 비해 역방향에서는 2배의 플롭스가 필요하므로 일반적으로 2배 정도 느리게 변환됩니다(역방향의 경우 사이즈가 부자연스럽기 때문에, 때로는 더욱 느릴 수도 있습니다). 활성화는 일반적으로 대역폭이 제한되어 있으며, 일반적으로 순방향보다 역방향에서 더 많은 데이터를 읽어야 합니다. (예를 들어, 순방향 활성화 시 한 번 씩 읽고 쓰지만, 역방향 활성화에서는 순방향 gradOutput과 출력에 대해 총 두 번 읽고 gradInput에 대해 한 번 씁니다.)
+
+보다시피, GPU 메모리를 절약하거나 작업 속도를 높일 수 있는 몇 가지 방법이 있습니다.
+이제 GPU 활용과 계산 속도에 영향을 주는 것이 무엇인지를 이해했으므로, [Methods and tools for efficient training on a single GPU](perf_train_gpu_one) 문서 페이지를 참조하여 성능 최적화 기법에 대해 알아보세요.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_sharing.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_sharing.md
new file mode 100644
index 0000000000000000000000000000000000000000..3811507796627522c8e91c229b2cbbe9786eb7f0
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_sharing.md
@@ -0,0 +1,232 @@
+
+
+# 모델 공유하기[[share-a-model]]
+
+지난 두 튜토리얼에서 분산 설정을 위해 PyTorch, Keras 및 🤗 Accelerate를 사용하여 모델을 미세 조정하는 방법을 보았습니다. 다음 단계는 모델을 커뮤니티와 공유하는 것입니다! Hugging Face는 인공지능의 민주화를 위해 모두에게 지식과 자원을 공개적으로 공유해야 한다고 믿습니다. 다른 사람들이 시간과 자원을 절약할 수 있도록 커뮤니티에 모델을 공유하는 것을 고려해 보세요.
+
+이 튜토리얼에서 [Model Hub](https://huggingface.co/models)에서 훈련되거나 미세 조정 모델을 공유하는 두 가지 방법에 대해 알아봅시다:
+
+- API를 통해 파일을 Hub에 푸시합니다.
+- 웹사이트를 통해 파일을 Hub로 끌어다 놓습니다.
+
+
+
+
+
+커뮤니티에 모델을 공유하려면, [huggingface.co](https://huggingface.co/join)에 계정이 필요합니다. 기존 조직에 가입하거나 새로 만들 수도 있습니다.
+
+
+
+## 저장소 특징[[repository-features]]
+
+모델 허브의 각 저장소는 일반적인 GitHub 저장소처럼 작동합니다. 저장소는 버전 관리, 커밋 기록, 차이점 시각화 기능을 제공합니다.
+
+모델 허브에 내장된 버전 관리는 git 및 [git-lfs](https://git-lfs.github.com/)를 기반으로 합니다. 즉, 하나의 모델을 하나의 저장소로 취급하여 접근 제어 및 확장성이 향상됩니다. 버전 제어는 커밋 해시, 태그 또는 브랜치로 모델의 특정 버전을 고정하는 방법인 *revision*을 허용합니다.
+
+따라서 `revision` 매개변수를 사용하여 특정 모델 버전을 가져올 수 있습니다:
+
+```py
+>>> model = AutoModel.from_pretrained(
+... "julien-c/EsperBERTo-small", revision="4c77982" # tag name, or branch name, or commit hash
+... )
+```
+
+또한 저장소에서 파일을 쉽게 편집할 수 있으며, 커밋 기록과 차이를 볼 수 있습니다:
+
+
+
+## 설정[[setup]]
+
+모델을 허브에 공유하기 전에 Hugging Face 자격 증명이 필요합니다. 터미널에 액세스할 수 있는 경우, 🤗 Transformers가 설치된 가상 환경에서 다음 명령을 실행합니다. 그러면 Hugging Face 캐시 폴더(기본적으로 `~/.cache/`)에 액세스 토큰을 저장합니다:
+
+```bash
+huggingface-cli login
+```
+
+Jupyter 또는 Colaboratory와 같은 노트북을 사용 중인 경우, [`huggingface_hub`](https://huggingface.co/docs/hub/adding-a-library) 라이브러리가 설치되었는지 확인하세요. 이 라이브러리를 사용하면 API로 허브와 상호 작용할 수 있습니다.
+
+```bash
+pip install huggingface_hub
+```
+
+그런 다음 `notebook_login`로 허브에 로그인하고, [여기](https://huggingface.co/settings/token) 링크에서 로그인할 토큰을 생성합니다:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## 프레임워크 간 모델 변환하기[[convert-a-model-for-all-frameworks]]
+
+다른 프레임워크로 작업하는 사용자가 모델을 사용할 수 있도록 하려면, PyTorch 및 TensorFlow 체크포인트를 모두 사용하여 모델을 변환하고 업로드하는 것이 좋습니다. 이 단계를 건너뛰어도 사용자는 다른 프레임워크에서 모델을 가져올 수 있지만, 🤗 Transformers가 체크포인트를 즉석에서 변환해야 하므로 속도가 느려질 수 있습니다.
+
+체크포인트를 다른 프레임워크로 변환하는 것은 쉽습니다. PyTorch 및 TensorFlow가 설치되어 있는지 확인한 다음(설치 지침은 [여기](installation) 참조) 다른 프레임워크에서 작업에 대한 특정 모델을 찾습니다.
+
+
+
+체크포인트를 TensorFlow에서 PyTorch로 변환하려면 `from_tf=True`를 지정하세요:
+
+```py
+>>> pt_model = DistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_tf=True)
+>>> pt_model.save_pretrained("path/to/awesome-name-you-picked")
+```
+
+
+체크포인트를 PyTorch에서 TensorFlow로 변환하려면 `from_pt=True`를 지정하세요:
+
+```py
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("path/to/awesome-name-you-picked", from_pt=True)
+```
+
+그런 다음 새로운 체크포인트와 함께 새로운 TensorFlow 모델을 저장할 수 있습니다:
+
+```py
+>>> tf_model.save_pretrained("path/to/awesome-name-you-picked")
+```
+
+
+Flax에서 모델을 사용하는 경우, PyTorch에서 Flax로 체크포인트를 변환할 수도 있습니다:
+
+```py
+>>> flax_model = FlaxDistilBertForSequenceClassification.from_pretrained(
+... "path/to/awesome-name-you-picked", from_pt=True
+... )
+```
+
+
+
+## 훈련 중 모델 푸시하기[[push-a-model-during-training]]
+
+
+
+
+
+모델을 허브에 공유하는 것은 추가 매개변수나 콜백을 추가하는 것만큼 간단합니다. [미세 조정 튜토리얼](training)에서 [`TrainingArguments`] 클래스는 하이퍼파라미터와 추가 훈련 옵션을 지정하는 곳이라는 것을 기억하세요. 이러한 훈련 옵션 중 하나는 모델을 허브로 직접 푸시하는 기능을 포함합니다. [`TrainingArguments`]에서 `push_to_hub=True`를 설정하세요:
+
+```py
+>>> training_args = TrainingArguments(output_dir="my-awesome-model", push_to_hub=True)
+```
+
+평소와 같이 훈련 인수를 [`Trainer`]에 전달합니다:
+
+```py
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... )
+```
+
+모델을 미세 조정한 후, [`Trainer`]에서 [`~transformers.Trainer.push_to_hub`]를 호출하여 훈련된 모델을 허브로 푸시하세요. 🤗 Transformers는 훈련 하이퍼파라미터, 훈련 결과 및 프레임워크 버전을 모델 카드에 자동으로 추가합니다!
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+[`PushToHubCallback`]을 사용하여 모델을 허브에 공유하려면, [`PushToHubCallback`]에 다음 인수를 정의하세요:
+
+- 출력된 모델의 파일 경로
+- 토크나이저
+- `{Hub 사용자 이름}/{모델 이름}` 형식의 `hub_model_id`
+
+```py
+>>> from transformers import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="./your_model_save_path", tokenizer=tokenizer, hub_model_id="your-username/my-awesome-model"
+... )
+```
+
+[`fit`](https://keras.io/api/models/model_training_apis/)에 콜백을 추가하면, 🤗 Transformers가 훈련된 모델을 허브로 푸시합니다:
+
+```py
+>>> model.fit(tf_train_dataset, validation_data=tf_validation_dataset, epochs=3, callbacks=push_to_hub_callback)
+```
+
+
+
+## `push_to_hub` 함수 사용하기[[use-the-pushtohub-function]]
+
+모델에서 직접 `push_to_hub`를 호출하여 허브에 업로드할 수도 있습니다.
+
+`push_to_hub`에 모델 이름을 지정하세요:
+
+```py
+>>> pt_model.push_to_hub("my-awesome-model")
+```
+
+이렇게 하면 사용자 이름 아래에 모델 이름 `my-awesome-model`로 저장소가 생성됩니다. 이제 사용자는 `from_pretrained` 함수를 사용하여 모델을 가져올 수 있습니다:
+
+```py
+>>> from transformers import AutoModel
+
+>>> model = AutoModel.from_pretrained("your_username/my-awesome-model")
+```
+
+조직에 속하고 모델을 조직 이름으로 대신 푸시하려면 `repo_id`에 추가하세요:
+
+```py
+>>> pt_model.push_to_hub("my-awesome-org/my-awesome-model")
+```
+
+`push_to_hub` 함수는 모델 저장소에 다른 파일을 추가하는 데에도 사용할 수 있습니다. 예를 들어 모델 저장소에 토크나이저를 추가할 수 있습니다:
+
+```py
+>>> tokenizer.push_to_hub("my-awesome-model")
+```
+
+또는 미세 조정된 PyTorch 모델의 TensorFlow 버전을 추가할 수도 있습니다:
+
+```py
+>>> tf_model.push_to_hub("my-awesome-model")
+```
+
+이제 Hugging Face 프로필로 이동하면, 새로 생성한 모델 저장소가 표시됩니다. **Files** 탭을 클릭하면 저장소에 업로드한 모든 파일이 표시됩니다.
+
+저장소에 파일을 만들고 업로드하는 방법에 대한 자세한 내용은 허브 설명서 [여기](https://huggingface.co/docs/hub/how-to-upstream)를 참조하세요.
+
+## 웹 인터페이스로 업로드하기[[upload-with-the-web-interface]]
+
+코드 없는 접근 방식을 선호하는 사용자는 허브의 웹 인터페이스를 통해 모델을 업로드할 수 있습니다. [huggingface.co/new](https://huggingface.co/new)를 방문하여 새로운 저장소를 생성하세요:
+
+
+
+여기서 모델에 대한 몇 가지 정보를 추가하세요:
+
+- 저장소의 **소유자**를 선택합니다. 이는 사용자 또는 사용자가 속한 조직일 수 있습니다.
+- 저장소 이름이 될 모델의 이름을 선택합니다.
+- 모델이 공개인지 비공개인지 선택합니다.
+- 모델의 라이센스 사용을 지정합니다.
+
+이제 **Files** 탭을 클릭하고 **Add file** 버튼을 클릭하여 새로운 파일을 저장소에 업로드합니다. 그런 다음 업로드할 파일을 끌어다 놓고 커밋 메시지를 추가하세요.
+
+
+
+## 모델 카드 추가하기[[add-a-model-card]]
+
+사용자가 모델의 기능, 제한, 잠재적 편향 및 윤리적 고려 사항을 이해할 수 있도록 저장소에 모델 카드를 추가하세요. 모델 카드는 `README.md` 파일에 정의되어 있습니다. 다음 방법으로 모델 카드를 추가할 수 있습니다:
+
+* `README.md` 파일을 수동으로 생성하여 업로드합니다.
+* 모델 저장소에서 **Edit model card** 버튼을 클릭합니다.
+
+모델 카드에 포함할 정보 유형에 대한 좋은 예는 DistilBert [모델 카드](https://huggingface.co/distilbert/distilbert-base-uncased)를 참조하세요. 모델의 탄소 발자국이나 위젯 예시 등 `README.md` 파일에서 제어할 수 있는 다른 옵션에 대한 자세한 내용은 [여기](https://huggingface.co/docs/hub/models-cards) 문서를 참조하세요.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_summary.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..568b9425335d7f95063daca468fe67f31913a2c1
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_summary.md
@@ -0,0 +1,107 @@
+
+
+# Transformer 모델군[[the-transformer-model-family]]
+
+2017년에 소개된 [기본 Transformer](https://arxiv.org/abs/1706.03762) 모델은 자연어 처리(NLP) 작업을 넘어 새롭고 흥미로운 모델들에 영감을 주었습니다. [단백질 접힘 구조 예측](https://huggingface.co/blog/deep-learning-with-proteins), [치타의 달리기 훈련](https://huggingface.co/blog/train-decision-transformers), [시계열 예측](https://huggingface.co/blog/time-series-transformers) 등을 위한 다양한 모델이 생겨났습니다. Transformer의 변형이 너무 많아서, 큰 그림을 놓치기 쉽습니다. 하지만 여기 있는 모든 모델의 공통점은 기본 Trasnformer 아키텍처를 기반으로 한다는 점입니다. 일부 모델은 인코더 또는 디코더만 사용하고, 다른 모델들은 인코더와 디코더를 모두 사용하기도 합니다. 이렇게 Transformer 모델군 내 상위 레벨에서의 차이점을 분류하고 검토하면 유용한 분류 체계를 얻을 수 있으며, 이전에 접해보지 못한 Transformer 모델들 또한 이해하는 데 도움이 될 것입니다.
+
+기본 Transformer 모델에 익숙하지 않거나 복습이 필요한 경우, Hugging Face 강의의 [트랜스포머는 어떻게 동작하나요?](https://huggingface.co/course/chapter1/4?fw=pt) 챕터를 확인하세요.
+
+
+
+
+
+## 컴퓨터 비전[[computer-vision]]
+
+
+
+### 합성곱 네트워크[[convolutional-network]]
+
+[Vision Transformer](https://arxiv.org/abs/2010.11929)가 확장성과 효율성을 입증하기 전까지 오랫동안 합성곱 네트워크(CNN)가 컴퓨터 비전 작업의 지배적인 패러다임이었습니다. 그럼에도 불구하고, 이동 불변성(translation invariance)과 같은 CNN의 우수한 부분이 도드라지기 때문에 몇몇 (특히 특정 과업에서의) Transformer 모델은 아키텍처에 합성곱을 통합하기도 했습니다. [ConvNeXt](model_doc/convnext)는 이런 관례를 뒤집어 CNN을 현대화하기 위해 Transformer의 디자인을 차용합니다. 예를 들면 ConvNeXt는 겹치지 않는 슬라이딩 창(sliding window)을 사용하여 이미지를 패치화하고, 더 큰 커널로 전역 수용 필드(global receptive field)를 확장시킵니다. ConvNeXt는 또한 메모리 효율을 높이고 성능을 향상시키기 위해 여러 레이어 설계를 선택하기 때문에 Transformer와 견줄만합니다!
+
+### 인코더[[cv-encoder]]
+
+[Vision Transformer(ViT)](model_doc/vit)는 합성곱 없는 컴퓨터 비전 작업의 막을 열었습니다. ViT는 표준 Transformer 인코더를 사용하지만, 가장 큰 혁신은 이미지를 처리하는 방식이었습니다. 문장을 토큰으로 분할하는 것처럼 이미지를 고정된 크기의 패치로 분할하고, 이를 사용하여 임베딩을 생성합니다. ViT는 Transformer의 효율적인 아키텍처를 활용하여 훈련에 더 적은 자원을 사용하면서도 당시 CNN에 비견하는 결과를 입증했습니다. 그리고 ViT를 뒤이어 분할(segmentation)과 같은 고밀도 비전 작업과 탐지 작업도 다룰 수 있는 다른 비전 모델이 등장했습니다.
+
+이러한 모델 중 하나가 [Swin](model_doc/swin) Transformer입니다. 이 모델은 작은 크기의 패치에서 계층적 특징 맵(CNN 👀과 같지만 ViT와는 다름)을 만들고 더 깊은 레이어의 인접 패치와 병합합니다. 어텐션(Attention)은 지역 윈도우 내에서만 계산되며, 모델이 더 잘 학습할 수 있도록 어텐션 레이어 간에 윈도우를 이동하며 연결을 생성합니다. Swin Transformer는 계층적 특징 맵을 생성할 수 있으므로, 분할(segmentation)과 탐지와 같은 고밀도 예측 작업에 적합합니다. [SegFormer](model_doc/segformer) 역시 Transformer 인코더를 사용하여 계층적 특징 맵을 구축하지만, 상단에 간단한 다층 퍼셉트론(MLP) 디코더를 추가하여 모든 특징 맵을 결합하고 예측을 수행합니다.
+
+BeIT와 ViTMAE와 같은 다른 비전 모델은 BERT의 사전훈련 목표(objective)에서 영감을 얻었습니다. [BeIT](model_doc/beit)는 *마스크드 이미지 모델링(MIM)*으로 사전훈련되며, 이미지 패치는 임의로 마스킹되고 이미지도 시각적 토큰으로 토큰화됩니다. BeIT는 마스킹된 패치에 해당하는 시각적 토큰을 예측하도록 학습됩니다. [ViTMAE](model_doc/vitmae)도 비슷한 사전훈련 목표가 있지만, 시각적 토큰 대신 픽셀을 예측해야 한다는 점이 다릅니다. 특이한 점은 이미지 패치의 75%가 마스킹되어 있다는 것입니다! 디코더는 마스킹된 토큰과 인코딩된 패치에서 픽셀을 재구성합니다. 사전훈련이 끝나면 디코더는 폐기되고 인코더는 다운스트림 작업에 사용할 준비가 됩니다.
+
+### 디코더[[cv-decoder]]
+
+대부분의 비전 모델은 인코더에 의존하여 이미지 표현을 학습하기 때문에 디코더 전용 비전 모델은 드뭅니다. 하지만 이미지 생성 등의 사례의 경우, GPT-2와 같은 텍스트 생성 모델에서 보았듯이 디코더가 가장 적합합니다. [ImageGPT](model_doc/imagegpt)는 GPT-2와 동일한 아키텍처를 사용하지만, 시퀀스의 다음 토큰을 예측하는 대신 이미지의 다음 픽셀을 예측합니다. ImageGPT는 이미지 생성 뿐만 아니라 이미지 분류를 위해 미세 조정할 수도 있습니다.
+
+### 인코더-디코더[[cv-encoder-decoder]]
+
+비전 모델은 일반적으로 인코더(백본으로도 알려짐)를 사용하여 중요한 이미지 특징을 추출한 후, 이를 Transformer 디코더로 전달합니다. [DETR](model_doc/detr)에 사전훈련된 백본이 있지만, 객체 탐지를 위해 완전한 Transformer 인코더-디코더 아키텍처도 사용합니다. 인코더는 이미지 표현을 학습하고 이를 디코더에서 객체 쿼리(각 객체 쿼리는 이미지의 영역 또는 객체에 중점을 두고 학습된 임베딩)와 결합합니다. DETR은 각 객체 쿼리에 대한 바운딩 박스 좌표와 클래스 레이블을 예측합니다.
+
+## 자연어처리[[natural-language-processing]]
+
+
+
+### 인코더[[nlp-encoder]]
+
+[BERT](model_doc/bert)는 인코더 전용 Transformer로, 다른 토큰을 보고 소위 "부정 행위"를 저지르는 걸 막기 위해 입력에서 특정 토큰을 임의로 마스킹합니다. 사전훈련의 목표는 컨텍스트를 기반으로 마스킹된 토큰을 예측하는 것입니다. 이를 통해 BERT는 왼쪽과 오른쪽 컨텍스트를 충분히 활용하여 입력에 대해 더 깊고 풍부한 표현을 학습할 수 있습니다. 그러나 BERT의 사전훈련 전략에는 여전히 개선의 여지가 남아 있었습니다. [RoBERTa](model_doc/roberta)는 더 긴 시간 동안 더 큰 배치에 대한 훈련을 포함하고, 전처리 중에 한 번만 마스킹하는 것이 아니라 각 에폭에서 토큰을 임의로 마스킹하고, 다음 문장 예측 목표를 제거하는 새로운 사전훈련 방식을 도입함으로써 이를 개선했습니다.
+
+성능 개선을 위한 전략으로 모델 크기를 키우는 것이 지배적입니다. 하지만 큰 모델을 훈련하려면 계산 비용이 많이 듭니다. 계산 비용을 줄이는 한 가지 방법은 [DistilBERT](model_doc/distilbert)와 같이 작은 모델을 사용하는 것입니다. DistilBERT는 압축 기법인 [지식 증류(knowledge distillation)](https://arxiv.org/abs/1503.02531)를 사용하여, 거의 모든 언어 이해 능력을 유지하면서 더 작은 버전의 BERT를 만듭니다.
+
+그러나 대부분의 Transformer 모델에 더 많은 매개변수를 사용하는 경향이 이어졌고, 이에 따라 훈련 효율성을 개선하는 것에 중점을 둔 새로운 모델이 등장했습니다. [ALBERT](model_doc/albert)는 두 가지 방법으로 매개변수 수를 줄여 메모리 사용량을 줄였습니다. 바로 큰 어휘를 두 개의 작은 행렬로 분리하는 것과 레이어가 매개변수를 공유하도록 하는 것입니다. [DeBERTa](model_doc/deberta)는 단어와 그 위치를 두 개의 벡터로 개별적으로 인코딩하는 분리된(disentangled) 어텐션 메커니즘을 추가했습니다. 어텐션은 단어와 위치 임베딩을 포함하는 단일 벡터 대신 이 별도의 벡터에서 계산됩니다. [Longformer](model_doc/longformer)는 특히 시퀀스 길이가 긴 문서를 처리할 때, 어텐션을 더 효율적으로 만드는 것에 중점을 두었습니다. 지역(local) 윈도우 어텐션(각 토큰 주변의 고정된 윈도우 크기에서만 계산되는 어텐션)과 전역(global) 어텐션(분류를 위해 `[CLS]`와 같은 특정 작업 토큰에만 해당)의 조합을 사용하여 전체(full) 어텐션 행렬 대신 희소(sparse) 어텐션 행렬을 생성합니다.
+
+### 디코더[[nlp-decoder]]
+
+[GPT-2](model_doc/gpt2)는 시퀀스에서 다음 단어를 예측하는 디코더 전용 Transformer입니다. 토큰을 오른쪽으로 마스킹하여 모델이 이전 토큰을 보고 "부정 행위"를 하지 못하도록 합니다. GPT-2는 방대한 텍스트에 대해 사전훈련하여 텍스트가 일부만 정확하거나 사실인 경우에도 상당히 능숙하게 텍스트를 생성할 수 있게 되었습니다. 하지만 GPT-2는 BERT가 사전훈련에서 갖는 양방향 컨텍스트가 부족하기 때문에 특정 작업에 적합하지 않았습니다. [XLNET](model_doc/xlnet)은 양방향 훈련이 가능한 permutation language modeling objective(PLM)를 사용하여 BERT와 GPT-2의 사전훈련 목표에 대한 장점을 함께 가지고 있습니다.
+
+GPT-2 이후, 언어 모델은 더욱 거대해졌고 현재는 *대규모 언어 모델(LLM)*로 알려져 있습니다. 충분히 큰 데이터 세트로 사전훈련된 LLM은 퓨샷(few-shot) 또는 제로샷(zero-shot) 학습을 수행합니다. [GPT-J](model_doc/gptj)는 6B 크기의 매개변수가 있고 400B 크기의 토큰으로 훈련된 LLM입니다. GPT-J에 이어 디코더 전용 모델군인 [OPT](model_doc/opt)가 등장했으며, 이 중 가장 큰 모델은 175B 크기이고 180B 크기의 토큰으로 훈련되었습니다. [BLOOM](model_doc/bloom)은 비슷한 시기에 출시되었으며, 이 중 가장 큰 모델은 176B 크기의 매개변수가 있고 46개의 언어와 13개의 프로그래밍 언어로 된 366B 크기의 토큰으로 훈련되었습니다.
+
+### 인코더-디코더[[nlp-encoder-decoder]]
+
+[BART](model_doc/bart)는 기본 Transformer 아키텍처를 유지하지만, 일부 텍스트 스팬(span)이 단일 `마스크` 토큰으로 대체되는 *text infilling* 변형으로 사전훈련 목표를 수정합니다. 디코더는 변형되지 않은 토큰(향후 토큰은 마스킹됨)을 예측하고 인코더의 은닉 상태를 사용하여 이 작업을 돕습니다. [Pegasus](model_doc/pegasus)는 BART와 유사하지만, Pegasus는 텍스트 스팬 대신 전체 문장을 마스킹합니다. Pegasus는 마스크드 언어 모델링 외에도 gap sentence generation(GSG)로 사전훈련됩니다. GSG는 문서에 중요한 문장 전체를 마스킹하여 `마스크` 토큰으로 대체하는 것을 목표로 합니다. 디코더는 남은 문장에서 출력을 생성해야 합니다. [T5](model_doc/t5)는 특정 접두사를 사용하여 모든 NLP 작업을 텍스트 투 텍스트 문제로 변환하는 더 특수한 모델입니다. 예를 들어, 접두사 `Summarize:`은 요약 작업을 나타냅니다. T5는 지도(GLUE 및 SuperGLUE) 훈련과 자기지도 훈련(토큰의 15%를 임의로 샘플링하여 제거)으로 사전훈련됩니다.
+
+## 오디오[[audio]]
+
+
+
+### 인코더[[audio-encoder]]
+
+[Wav2Vec2](model_doc/wav2vec2)는 Transformer 인코더를 사용하여 원본 오디오 파형(raw audio waveform)에서 직접 음성 표현을 학습합니다. 허위 음성 표현 세트에서 실제 음성 표현을 판별하는 대조 작업으로 사전훈련됩니다. [HuBERT](model_doc/hubert)는 Wav2Vec2와 유사하지만 훈련 과정이 다릅니다. 타겟 레이블이 유사한 오디오 세그먼트가 클러스터에 할당되어 은닉 단위(unit)가 되는 군집화(clustering) 단계에서 생성됩니다. 은닉 단위는 예측을 위한 임베딩에 매핑됩니다.
+
+### 인코더-디코더[[audio-encoder-decoder]]
+
+[Speech2Text](model_doc/speech_to_text)는 자동 음성 인식(ASR) 및 음성 번역을 위해 고안된 음성 모델입니다. 이 모델은 오디오 파형에서 추출한 log mel-filter bank 특징을 채택하고 자기회귀 방식으로 사전훈련하여, 전사본 또는 번역을 만듭니다. [Whisper](model_doc/whisper)은 ASR 모델이지만, 다른 많은 음성 모델과 달리 제로샷 성능을 위해 대량의 ✨ 레이블이 지정된 ✨ 오디오 전사 데이터에 대해 사전훈련됩니다. 데이터 세트의 큰 묶음에는 영어가 아닌 언어도 포함되어 있어서 자원이 적은 언어에도 Whisper를 사용할 수 있습니다. 구조적으로, Whisper는 Speech2Text와 유사합니다. 오디오 신호는 인코더에 의해 인코딩된 log-mel spectrogram으로 변환됩니다. 디코더는 인코더의 은닉 상태와 이전 토큰으로부터 자기회귀 방식으로 전사를 생성합니다.
+
+## 멀티모달[[multimodal]]
+
+
+
+### 인코더[[mm-encoder]]
+
+[VisualBERT](model_doc/visual_bert)는 BERT 이후에 출시된 비전 언어 작업을 위한 멀티모달 모델입니다. 이 모델은 BERT와 사전훈련된 객체 탐지 시스템을 결합하여 이미지 특징을 시각 임베딩으로 추출하고, 텍스트 임베딩과 함께 BERT로 전달합니다. VisualBERT는 마스킹되지 않은 텍스트와 시각 임베딩을 기반으로 마스킹된 텍스트를 예측하고, 텍스트가 이미지와 일치하는지 예측해야 합니다. ViT가 이미지 임베딩을 구하는 방식이 더 쉬웠기 때문에, ViT가 출시된 후 [ViLT](model_doc/vilt)는 아키텍처에 ViT를 채택했습니다. 이미지 임베딩은 텍스트 임베딩과 함께 처리됩니다. 여기에서, ViLT는 이미지 텍스트 매칭, 마스크드 언어 모델링, 전체 단어 마스킹을 통해 사전훈련됩니다.
+
+[CLIP](model_doc/clip)은 다른 접근 방식을 사용하여 (`이미지`, `텍스트`)의 쌍 예측을 수행합니다. (`이미지`, `텍스트`) 쌍에서의 이미지와 텍스트 임베딩 간의 유사도를 최대화하기 위해 4억 개의 (`이미지`, `텍스트`) 쌍 데이터 세트에 대해 이미지 인코더(ViT)와 텍스트 인코더(Transformer)를 함께 훈련합니다. 사전훈련 후, 자연어를 사용하여 이미지가 주어진 텍스트를 예측하거나 그 반대로 예측하도록 CLIP에 지시할 수 있습니다. [OWL-ViT](model_doc/owlvit)는 CLIP을 제로샷 객체 탐지를 위한 백본(backbone)으로 사용하여 CLIP 상에 구축됩니다. 사전훈련 후, 객체 탐지 헤드가 추가되어 (`클래스`, `바운딩 박스`) 쌍에 대한 집합(set) 예측을 수행합니다.
+
+### 인코더-디코더[[mm-encoder-decoder]]
+
+광학 문자 인식(OCR)은 이미지를 이해하고 텍스트를 생성하기 위해 다양한 구성 요소를 필요로 하는 전통적인 텍스트 인식 작업입니다. [TrOCR](model_doc/trocr)은 종단간(end-to-end) Transformer를 사용하여 이 프로세스를 간소화합니다. 인코더는 이미지 이해를 위한 ViT 방식의 모델이며 이미지를 고정된 크기의 패치로 처리합니다. 디코더는 인코더의 은닉 상태를 받아서 자기회귀 방식으로 텍스트를 생성합니다. [Donut](model_doc/donut)은 OCR 기반 접근 방식에 의존하지 않는 더 일반적인 시각 문서 이해 모델입니다. 이 모델은 Swin Transformer를 인코더로, 다국어 BART를 디코더로 사용합니다. Donut은 이미지와 텍스트 주석을 기반으로 다음 단어를 예측하여 텍스트를 읽도록 사전훈련됩니다. 디코더는 프롬프트가 주어지면 토큰 시퀀스를 생성합니다. 프롬프트는 각 다운스트림 작업에 대한 특수 토큰으로 표현됩니다. 예를 들어, 문서 파싱(parsing)에는 인코더의 은닉 상태와 결합되어 문서를 정형 출력 형식(JSON)으로 파싱하는 특수 `파싱` 토큰이 있습니다.
+
+## 강화 학습[[reinforcement-learning]]
+
+
+
+### 디코더[[rl-decoder]]
+
+Decision 및 Trajectory Transformer는 상태(state), 행동(action), 보상(reward)을 시퀀스 모델링 문제로 표현합니다. [Decision Transformer](model_doc/decision_transformer)는 기대 보상(returns-to-go), 과거 상태 및 행동을 기반으로 미래의 원하는 수익(return)으로 이어지는 일련의 행동을 생성합니다. 마지막 *K* 시간 스텝(timestep)에 대해, 세 가지 모달리티는 각각 토큰 임베딩으로 변환되고 GPT와 같은 모델에 의해 처리되어 미래의 액션 토큰을 예측합니다. [Trajectory Transformer](model_doc/trajectory_transformer)도 상태, 행동, 보상을 토큰화하여 GPT 아키텍처로 처리합니다. 보상 조건에 중점을 둔 Decision Transformer와 달리 Trajectory Transformer는 빔 서치(beam search)로 미래 행동을 생성합니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/modular_transformers.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/modular_transformers.md
new file mode 100644
index 0000000000000000000000000000000000000000..096dd4f13a9889dad2c3ab0a6ca3c1308ab952b2
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/modular_transformers.md
@@ -0,0 +1,96 @@
+# 모듈식 트랜스포머 [[modular-transformers]]
+
+`transformers`는 opinionated(자기 의견이 강한) 프레임워크이며, 우리의 철학은 다음의 [개념 가이드](./philosophy)에 정의되어 있습니다.
+
+이 철학의 핵심은 라이브러리의 [단일 모델, 단일 파일](https://huggingface.co/blog/transformers-design-philosophy) 측면에서 잘 나타납니다. 이 구성 요소의 단점은 파일 간에 구성 요소의 상속과 임포트 가능성을 제한한다는 것입니다.
+
+그 결과, 모델 구성 요소가 여러 파일에 걸쳐 반복되는 경향이 있습니다. `transformers`에는 모델 수만큼 많은 어텐션 레이어가 정의되어 있으며, 그 중 상당수는 서로 동일합니다. 안타깝게도, 수정과 변경 사항이 코드의 특정 부분에 적용되면서 독립적인 구현들이 서로 분기되는 경향이 있습니다.
+
+이 문제를 적절히 해결하기 위해, 우리는 라이브러리 전체에 "복사본"의 개념을 도입했습니다. 코드가 다른 코드의 복사본임을 나타내는 주석을 추가함으로써, CI 및 로컬 명령을 통해 복사본이 분기되지 않도록 강제할 수 있습니다. 그러나 복잡성이 낮더라도 이는 종종 매우 번거로운 작업입니다.
+
+마지막으로, 이 방식은 우리가 줄이고자 하는 상당한 오버헤드를 모델 기여 과정에 추가하게 됩니다. 이 접근 방식은 종종 모델 기여에 모델링 코드(~1,000줄), 프로세서(~500줄), 테스트, 문서 등을 추가해야 합니다. 모델 기여 PR은 대부분 3,000~5,000줄 이상의 코드를 추가하며, 이 중 많은 부분이 보일러플레이트(boilerplate) 코드입니다.
+
+이는 기여의 장벽을 높이며, 모듈식 트랜스포머를 통해 우리는 이러한 장벽을 훨씬 더 수용 가능한 수준으로 낮추고자 합니다.
+
+## 무엇인가요 [[what-is-it]]
+
+모듈식 트랜스포머는 모델 폴더에 "모듈식" 파일의 개념을 도입합니다. 이 모듈식 파일은 일반적으로 모델링/프로세싱 파일에서 허용되지 않는 코드를 허용하며, 이는 인접한 모델로부터의 임포트와 클래스 간의 상속을 허용합니다.
+
+이 모듈식 파일은 각각의 별도의 모듈에서 정의되었을 모델, 프로세서 및 구성 클래스를 정의합니다.
+
+마지막으로, 이 기능은 모듈식 파일을 "풀어내어" 단일 모델, 단일 파일 디렉토리 구조로 변환하는 새로운 `linter`를 도입합니다. 이 파일들은 스크립트가 실행될 때마다 자동으로 생성되며, 기여해야 할 내용을 모듈식 파일, 그리고 기여된 모델과 다른 모델 간의 차이점으로만 줄여줍니다.
+
+모델 사용자는 단일 파일 인터페이스를 임포트하고 사용하게 되므로, 여기에는 변화가 없을 것입니다. 이를 통해 간단한 기여를 가능하게 하면서도 우리의 철학을 유지하는 양쪽의 장점을 결합하고자 합니다.
+
+따라서 이는 `# Copied from` 마커의 대체품이며, 이전에 기여된 모델은 앞으로 몇 달 내에 새로운 모듈식 트랜스포머 형식으로 전환될 예정입니다.
+
+### 자세한 내용 [[details]]
+
+“linter”는 상속 구조를 풀어서 모듈화된 파일로부터 모든 단일 파일을 생성하며, Python 사용자들에게는 그 과정이 보이지 않도록 동작합니다. 현재 linter는 **단일** 수준의 상속만을 평탄화합니다.
+
+예를 들어:
+- 구성 클래스가 다른 클래스를 상속하고 인자를 추가/삭제하는 경우, 생성된 파일은 직접 참조(추가의 경우)하거나 완전히 제거합니다(삭제의 경우).
+- 클래스가 다른 클래스를 상속하는 경우, 예를 들어 class GemmaModel(LlamaModel): 의 경우, 종속성이 자동으로 추론됩니다. 모든 서브모듈은 슈퍼클래스로부터 자동으로 추론됩니다.
+
+토크나이저, 이미지 프로세서, 모델, 구성 등을 이 `modular` 파일에 모두 작성할 수 있으며, 해당 파일들이 자동으로 생성됩니다.
+
+### 시행 [[enforcement]]
+
+[TODO] 우리는 새로운 테스트를 도입하여 생성된 콘텐츠가 `modular_xxxx.py`에 있는 내용과 일치하는지 확인합니다.
+
+### 예시 [[examples]]
+
+여기 BERT와 RoBERTa의 간단한 예가 있습니다. 두 모델은 밀접하게 관련되어 있으며, 모델 구현의 차이는 임베딩 레이어의 변경에서만 있습니다.
+
+모델을 완전히 재정의하는 대신, `modular_roberta.py` 파일은 모델링 및 구성 클래스를 위해 다음과 같이 생겼습니다. (예시를 위해, 토크나이저는 매우 다르므로 일단 무시합니다.)
+
+```python
+from torch import nn
+from ..bert.configuration_bert import BertConfig
+from ..bert.modeling_bert import (
+ BertModel,
+ BertEmbeddings,
+ BertForMaskedLM
+)
+
+# RoBERTa 구성은 BERT의 구성과 동일합니다
+class RobertaConfig(BertConfig):
+ model_type = 'roberta'
+
+# 여기서 패딩 ID 차이를 강조하기 위해 임베딩을 재정의하고, 위치 임베딩을 재정의합니다
+class RobertaEmbeddings(BertEmbeddings):
+ def __init__(self, config):
+ super().__init__(config())
+
+ self.padding_idx = config.pad_token_id
+ self.position_embeddings = nn.Embedding(
+ config.max_position_embeddings, config.hidden_size, padding_idx=self.padding_idx
+ )
+
+# RoBERTa 모델은 임베딩 레이어를 제외하면 BERT 모델과 동일합니다.
+# 위에서 임베딩을 재정의했으므로, 여기서는 추가 작업이 필요 없습니다
+class RobertaModel(BertModel):
+ def __init__(self, config):
+ super().__init__(config)
+ self.embeddings = RobertaEmbeddings(config)
+
+# 헤드는 이제 내부에서 올바른 `RobertaModel`을 재정의하기만 하면 됩니다
+class RobertaForMaskedLM(BertForMaskedLM):
+ def __init__(self, config):
+ super().__init__(config)
+ self.model = RobertaModel(config)
+```
+
+정의한 종속성을 사용하지 않으면 다음과 같은 오류가 발생합니다:
+
+```bash
+ValueError: You defined `RobertaEmbeddings` in the modular_roberta.py, it should be used
+ when you define `BertModel`, as it is one of it's direct dependencies. Make sure
+ you use it in the `__init__` function.
+```
+
+또한, 다음에서 예시 목록을 찾을 수 있습니다:
+
+## 무엇이 아닌가요 [[what-it-is-not]]
+
+(아직은?) 모델링 코드를 대체하는 것은 아닙니다. 그리고 여러분의 모델이 지금까지 존재했던 다른 어떤 것에도 기반하지 않는다면, 기존과 같이 `modeling` 파일을 추가할 수 있습니다.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/multilingual.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/multilingual.md
new file mode 100644
index 0000000000000000000000000000000000000000..c0eee024358f3e1a42ed08834183e810a271d8f8
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/multilingual.md
@@ -0,0 +1,192 @@
+
+
+# 다국어 모델 추론하기[[multilingual-models-for-inference]]
+
+[[open-in-colab]]
+
+🤗 Transformers에는 여러 종류의 다국어(multilingual) 모델이 있으며, 단일 언어(monolingual) 모델과 추론 시 사용법이 다릅니다.
+그렇다고 해서 *모든* 다국어 모델의 사용법이 다른 것은 아닙니다.
+
+[google-bert/bert-base-multilingual-uncased](https://huggingface.co/google-bert/bert-base-multilingual-uncased)와 같은 몇몇 모델은 단일 언어 모델처럼 사용할 수 있습니다.
+이번 가이드에서 다국어 모델의 추론 시 사용 방법을 알아볼 것입니다.
+
+## XLM[[xlm]]
+
+XLM에는 10가지 체크포인트(checkpoint)가 있는데, 이 중 하나만 단일 언어입니다.
+나머지 체크포인트 9개는 언어 임베딩을 사용하는 체크포인트와 그렇지 않은 체크포인트의 두 가지 범주로 나눌 수 있습니다.
+
+### 언어 임베딩을 사용하는 XLM[[xlm-with-language-embeddings]]
+
+다음 XLM 모델은 추론 시에 언어 임베딩을 사용합니다:
+
+- `FacebookAI/xlm-mlm-ende-1024` (마스킹된 언어 모델링, 영어-독일어)
+- `FacebookAI/xlm-mlm-enfr-1024` (마스킹된 언어 모델링, 영어-프랑스어)
+- `FacebookAI/xlm-mlm-enro-1024` (마스킹된 언어 모델링, 영어-루마니아어)
+- `FacebookAI/xlm-mlm-xnli15-1024` (마스킹된 언어 모델링, XNLI 데이터 세트에서 제공하는 15개 국어)
+- `FacebookAI/xlm-mlm-tlm-xnli15-1024` (마스킹된 언어 모델링 + 번역, XNLI 데이터 세트에서 제공하는 15개 국어)
+- `FacebookAI/xlm-clm-enfr-1024` (Causal language modeling, 영어-프랑스어)
+- `FacebookAI/xlm-clm-ende-1024` (Causal language modeling, 영어-독일어)
+
+언어 임베딩은 모델에 전달된 `input_ids`와 동일한 shape의 텐서로 표현됩니다.
+이러한 텐서의 값은 사용된 언어에 따라 다르며 토크나이저의 `lang2id` 및 `id2lang` 속성에 의해 식별됩니다.
+
+다음 예제에서는 `FacebookAI/xlm-clm-enfr-1024` 체크포인트(코잘 언어 모델링(causal language modeling), 영어-프랑스어)를 가져옵니다:
+
+```py
+>>> import torch
+>>> from transformers import XLMTokenizer, XLMWithLMHeadModel
+
+>>> tokenizer = XLMTokenizer.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+>>> model = XLMWithLMHeadModel.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+```
+
+토크나이저의 `lang2id` 속성은 모델의 언어와 해당 ID를 표시합니다:
+
+```py
+>>> print(tokenizer.lang2id)
+{'en': 0, 'fr': 1}
+```
+
+다음으로, 예제 입력을 만듭니다:
+
+```py
+>>> input_ids = torch.tensor([tokenizer.encode("Wikipedia was used to")]) # 배치 크기는 1입니다
+```
+
+언어 ID를 `"en"`으로 설정해 언어 임베딩을 정의합니다.
+언어 임베딩은 영어의 언어 ID인 `0`으로 채워진 텐서입니다.
+이 텐서는 `input_ids`와 같은 크기여야 합니다.
+
+```py
+>>> language_id = tokenizer.lang2id["en"] # 0
+>>> langs = torch.tensor([language_id] * input_ids.shape[1]) # torch.tensor([0, 0, 0, ..., 0])
+
+>>> # (batch_size, sequence_length) shape의 텐서가 되도록 만듭니다.
+>>> langs = langs.view(1, -1) # 이제 [1, sequence_length] shape이 되었습니다(배치 크기는 1입니다)
+```
+
+이제 `input_ids`와 언어 임베딩을 모델로 전달합니다:
+
+```py
+>>> outputs = model(input_ids, langs=langs)
+```
+
+[run_generation.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-generation/run_generation.py) 스크립트로 `xlm-clm` 체크포인트를 사용해 텍스트와 언어 임베딩을 생성할 수 있습니다.
+
+### 언어 임베딩을 사용하지 않는 XLM[[xlm-without-language-embeddings]]
+
+다음 XLM 모델은 추론 시에 언어 임베딩이 필요하지 않습니다:
+
+- `FacebookAI/xlm-mlm-17-1280` (마스킹된 언어 모델링, 17개 국어)
+- `FacebookAI/xlm-mlm-100-1280` (마스킹된 언어 모델링, 100개 국어)
+
+이전의 XLM 체크포인트와 달리 이 모델은 일반 문장 표현에 사용됩니다.
+
+## BERT[[bert]]
+
+다음 BERT 모델은 다국어 태스크에 사용할 수 있습니다:
+
+- `google-bert/bert-base-multilingual-uncased` (마스킹된 언어 모델링 + 다음 문장 예측, 102개 국어)
+- `google-bert/bert-base-multilingual-cased` (마스킹된 언어 모델링 + 다음 문장 예측, 104개 국어)
+
+이러한 모델은 추론 시에 언어 임베딩이 필요하지 않습니다.
+문맥에서 언어를 식별하고, 식별된 언어로 추론합니다.
+
+## XLM-RoBERTa[[xlmroberta]]
+
+다음 XLM-RoBERTa 또한 다국어 다국어 태스크에 사용할 수 있습니다:
+
+- `FacebookAI/xlm-roberta-base` (마스킹된 언어 모델링, 100개 국어)
+- `FacebookAI/xlm-roberta-large` (마스킹된 언어 모델링, 100개 국어)
+
+XLM-RoBERTa는 100개 국어에 대해 새로 생성되고 정제된 2.5TB 규모의 CommonCrawl 데이터로 학습되었습니다.
+이전에 공개된 mBERT나 XLM과 같은 다국어 모델에 비해 분류, 시퀀스 라벨링, 질의 응답과 같은 다운스트림(downstream) 작업에서 이점이 있습니다.
+
+## M2M100[[m2m100]]
+
+다음 M2M100 모델 또한 다국어 다국어 태스크에 사용할 수 있습니다:
+
+- `facebook/m2m100_418M` (번역)
+- `facebook/m2m100_1.2B` (번역)
+
+이 예제에서는 `facebook/m2m100_418M` 체크포인트를 가져와서 중국어를 영어로 번역합니다.
+토크나이저에서 번역 대상 언어(source language)를 설정할 수 있습니다:
+
+```py
+>>> from transformers import M2M100ForConditionalGeneration, M2M100Tokenizer
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> chinese_text = "不要插手巫師的事務, 因為他們是微妙的, 很快就會發怒."
+
+>>> tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M", src_lang="zh")
+>>> model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M")
+```
+
+문장을 토큰화합니다:
+
+```py
+>>> encoded_zh = tokenizer(chinese_text, return_tensors="pt")
+```
+
+M2M100은 번역을 진행하기 위해 첫 번째로 생성되는 토큰은 번역할 언어(target language) ID로 강제 지정합니다.
+영어로 번역하기 위해 `generate` 메소드에서 `forced_bos_token_id`를 `en`으로 설정합니다:
+
+```py
+>>> generated_tokens = model.generate(**encoded_zh, forced_bos_token_id=tokenizer.get_lang_id("en"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+'Do not interfere with the matters of the witches, because they are delicate and will soon be angry.'
+```
+
+## MBart[[mbart]]
+
+다음 MBart 모델 또한 다국어 태스크에 사용할 수 있습니다:
+
+- `facebook/mbart-large-50-one-to-many-mmt` (일대다 다국어 번역, 50개 국어)
+- `facebook/mbart-large-50-many-to-many-mmt` (다대다 다국어 번역, 50개 국어)
+- `facebook/mbart-large-50-many-to-one-mmt` (다대일 다국어 번역, 50개 국어)
+- `facebook/mbart-large-50` (다국어 번역, 50개 국어)
+- `facebook/mbart-large-cc25`
+
+이 예제에서는 핀란드어를 영어로 번역하기 위해 `facebook/mbart-large-50-many-to-many-mmt` 체크포인트를 가져옵니다.
+토크나이저에서 번역 대상 언어(source language)를 설정할 수 있습니다:
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> fi_text = "Älä sekaannu velhojen asioihin, sillä ne ovat hienovaraisia ja nopeasti vihaisia."
+
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/mbart-large-50-many-to-many-mmt", src_lang="fi_FI")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
+```
+
+문장을 토큰화합니다:
+
+```py
+>>> encoded_en = tokenizer(en_text, return_tensors="pt")
+```
+
+MBart는 번역을 진행하기 위해 첫 번째로 생성되는 토큰은 번역할 언어(target language) ID로 강제 지정합니다.
+영어로 번역하기 위해 `generate` 메소드에서 `forced_bos_token_id`를 `en`으로 설정합니다:
+
+```py
+>>> generated_tokens = model.generate(**encoded_en, forced_bos_token_id=tokenizer.lang_code_to_id("en_XX"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+"Don't interfere with the wizard's affairs, because they are subtle, will soon get angry."
+```
+
+`facebook/mbart-large-50-many-to-one-mmt` 체크포인트를 사용하고 있다면, 첫 번째로 생성되는 토큰을 번역할 언어(target language) ID로 강제 지정할 필요는 없습니다.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/pad_truncation.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/pad_truncation.md
new file mode 100644
index 0000000000000000000000000000000000000000..9ee4dc839b8416f2114b0a12e7e86ada591926a6
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/pad_truncation.md
@@ -0,0 +1,68 @@
+
+
+# 패딩과 잘라내기[[padding-and-truncation]]
+
+배치 입력은 길이가 다른 경우가 많아서 고정 크기 텐서로 변환할 수 없습니다. 패딩과 잘라내기는 다양한 길이의 배치에서 직사각형 텐서를 생성할 수 있도록 이 문제를 해결하는 전략입니다. 패딩은 특수한 **패딩 토큰**을 추가하여 짧은 시퀀스가 배치에서 가장 긴 시퀀스 또는 모델에서 허용하는 최대 길이와 동일한 길이를 갖도록 합니다. 잘라내기는 긴 시퀀스를 잘라내어 패딩과 다른 방식으로 시퀀스의 길이를 동일하게 합니다.
+
+대부분의 경우 배치에 가장 긴 시퀀스의 길이로 패딩하고 모델이 허용할 수 있는 최대 길이로 잘라내는 것이 잘 작동합니다. 그러나 필요하다면 API가 지원하는 더 많은 전략을 사용할 수 있습니다. 필요한 인수는 `padding`, `truncation`, `max_length` 세 가지입니다.
+
+`padding` 인수는 패딩을 제어합니다. 불리언 또는 문자열일 수 있습니다:
+
+ - `True` 또는 `'longest'`: 배치에서 가장 긴 시퀀스로 패딩합니다(단일 시퀀스만 제공하는 경우 패딩이 적용되지 않습니다).
+ - `'max_length'`: `max_length` 인수가 지정한 길이로 패딩하거나, `max_length`가 제공되지 않은 경우(`max_length=None`) 모델에서 허용되는 최대 길이로 패딩합니다. 단일 시퀀스만 제공하는 경우에도 패딩이 적용됩니다.
+ - `False` 또는 `'do_not_pad'`: 패딩이 적용되지 않습니다. 이것이 기본 동작입니다.
+
+`truncation` 인수는 잘라낼 방법을 정합니다. 불리언 또는 문자열일 수 있습니다:
+
+ - `True` 또는 `longest_first`: `max_length` 인수가 지정한 최대 길이로 잘라내거나,
+ `max_length`가 제공되지 않은 경우(`max_length=None`) 모델에서 허용되는 최대 길이로 잘라냅니다.
+ 시퀀스 쌍에서 가장 긴 시퀀스의 토큰을 적절한 길이에 도달할 때까지 하나씩 제거합니다.
+ - `'only_second'`: `max_length` 인수가 지정한 최대 길이로 잘라내거나,
+ `max_length`가 제공되지 않은 경우(`max_length=None`) 모델에서 허용되는 최대 길이로 잘라냅니다.
+ 시퀀스 쌍(또는 시퀀스 쌍의 배치)가 제공된 경우 쌍의 두 번째 문장만 잘라냅니다.
+ - `'only_first'`: `max_length` 인수가 지정한 최대 길이로 잘라내거나,
+ `max_length`가 제공되지 않은 경우(`max_length=None`) 모델에서 허용되는 최대 길이로 잘라냅니다.
+ 시퀀스 쌍(또는 시퀀스 쌍의 배치)가 제공된 경우 쌍의 첫 번째 문장만 잘라냅니다.
+ - `False` 또는 `'do_not_truncate'`: 잘라내기를 적용하지 않습니다. 이것이 기본 동작입니다.
+
+`max_length` 인수는 패딩 및 잘라내기를 적용할 길이를 제어합니다. 이 인수는 정수 또는 `None`일 수 있으며, `None`일 경우 모델이 허용할 수 있는 최대 길이로 기본값이 설정됩니다. 모델에 특정한 최대 입력 길이가 없는 경우 `max_length`에 대한 잘라내기 또는 패딩이 비활성화됩니다.
+
+다음 표에는 패딩 및 잘라내기를 설정하는 권장 방법이 요약되어 있습니다.
+입력으로 시퀀스 쌍을 사용하는 경우, 다음 예제에서 `truncation=True`를 `['only_first', 'only_second', 'longest_first']`에서 선택한 `STRATEGY`, 즉 `truncation='only_second'` 또는 `truncation='longest_first'`로 바꾸면 앞서 설명한 대로 쌍의 두 시퀀스가 잘리는 방식을 제어할 수 있습니다.
+
+| 잘라내기 | 패딩 | 사용 방법 |
+|--------------------------------------|-----------------------------------|------------------------------------------------------------------------------------------|
+| 잘라내기 없음 | 패딩 없음 | `tokenizer(batch_sentences)` |
+| | 배치 내 최대 길이로 패딩 | `tokenizer(batch_sentences, padding=True)` 또는 |
+| | | `tokenizer(batch_sentences, padding='longest')` |
+| | 모델의 최대 입력 길이로 패딩 | `tokenizer(batch_sentences, padding='max_length')` |
+| | 특정 길이로 패딩 | `tokenizer(batch_sentences, padding='max_length', max_length=42)` |
+| | 다양한 길이로 패딩 | `tokenizer(batch_sentences, padding=True, pad_to_multiple_of=8)` |
+| 모델의 최대 입력 길이로 잘라내기 | 패딩 없음 | `tokenizer(batch_sentences, truncation=True)` 또는 |
+| | | `tokenizer(batch_sentences, truncation=STRATEGY)` |
+| | 배치 내 최대 길이로 패딩 | `tokenizer(batch_sentences, padding=True, truncation=True)` 또는 |
+| | | `tokenizer(batch_sentences, padding=True, truncation=STRATEGY)` |
+| | 모델의 최대 입력 길이로 패딩 | `tokenizer(batch_sentences, padding='max_length', truncation=True)` 또는 |
+| | | `tokenizer(batch_sentences, padding='max_length', truncation=STRATEGY)` |
+| | 특정 길이로 패딩 | 사용 불가 |
+| 특정 길이로 잘라내기 | 패딩 없음 | `tokenizer(batch_sentences, truncation=True, max_length=42)` 또는 |
+| | | `tokenizer(batch_sentences, truncation=STRATEGY, max_length=42)` |
+| | 배치 내 최대 길이로 패딩 | `tokenizer(batch_sentences, padding=True, truncation=True, max_length=42)` 또는 |
+| | | `tokenizer(batch_sentences, padding=True, truncation=STRATEGY, max_length=42)` |
+| | 모델의 최대 입력 길이로 패딩 | 사용 불가 |
+| | 특정 길이로 패딩 | `tokenizer(batch_sentences, padding='max_length', truncation=True, max_length=42)` 또는 |
+| | | `tokenizer(batch_sentences, padding='max_length', truncation=STRATEGY, max_length=42)` |
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/peft.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/peft.md
new file mode 100644
index 0000000000000000000000000000000000000000..d4ef0ba539e2de598a6d7504908f632c34e7c560
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/peft.md
@@ -0,0 +1,209 @@
+
+
+# 🤗 PEFT로 어댑터 가져오기 [[load-adapters-with-peft]]
+
+[[open-in-colab]]
+
+[Parameter-Efficient Fine Tuning (PEFT)](https://huggingface.co/blog/peft) 방법은 사전훈련된 모델의 매개변수를 미세 조정 중 고정시키고, 그 위에 훈련할 수 있는 매우 적은 수의 매개변수(어댑터)를 추가합니다. 어댑터는 작업별 정보를 학습하도록 훈련됩니다. 이 접근 방식은 완전히 미세 조정된 모델에 필적하는 결과를 생성하면서, 메모리 효율적이고 비교적 적은 컴퓨팅 리소스를 사용합니다.
+
+또한 PEFT로 훈련된 어댑터는 일반적으로 전체 모델보다 훨씬 작기 때문에 공유, 저장 및 가져오기가 편리합니다.
+
+
+
+ Hub에 저장된 OPTForCausalLM 모델의 어댑터 가중치는 최대 700MB에 달하는 모델 가중치의 전체 크기에 비해 약 6MB에 불과합니다.
+
+
+🤗 PEFT 라이브러리에 대해 자세히 알아보려면 [문서](https://huggingface.co/docs/peft/index)를 확인하세요.
+
+## 설정 [[setup]]
+
+🤗 PEFT를 설치하여 시작하세요:
+
+```bash
+pip install peft
+```
+
+새로운 기능을 사용해보고 싶다면, 다음 소스에서 라이브러리를 설치하는 것이 좋습니다:
+
+```bash
+pip install git+https://github.com/huggingface/peft.git
+```
+
+## 지원되는 PEFT 모델 [[supported-peft-models]]
+
+🤗 Transformers는 기본적으로 일부 PEFT 방법을 지원하며, 로컬이나 Hub에 저장된 어댑터 가중치를 가져오고 몇 줄의 코드만으로 쉽게 실행하거나 훈련할 수 있습니다. 다음 방법을 지원합니다:
+
+- [Low Rank Adapters](https://huggingface.co/docs/peft/conceptual_guides/lora)
+- [IA3](https://huggingface.co/docs/peft/conceptual_guides/ia3)
+- [AdaLoRA](https://arxiv.org/abs/2303.10512)
+
+🤗 PEFT와 관련된 다른 방법(예: 프롬프트 훈련 또는 프롬프트 튜닝) 또는 일반적인 🤗 PEFT 라이브러리에 대해 자세히 알아보려면 [문서](https://huggingface.co/docs/peft/index)를 참조하세요.
+
+
+## PEFT 어댑터 가져오기 [[load-a-peft-adapter]]
+
+🤗 Transformers에서 PEFT 어댑터 모델을 가져오고 사용하려면 Hub 저장소나 로컬 디렉터리에 `adapter_config.json` 파일과 어댑터 가중치가 포함되어 있는지 확인하십시오. 그런 다음 `AutoModelFor` 클래스를 사용하여 PEFT 어댑터 모델을 가져올 수 있습니다. 예를 들어 인과 관계 언어 모델용 PEFT 어댑터 모델을 가져오려면 다음 단계를 따르십시오:
+
+1. PEFT 모델 ID를 지정하십시오.
+2. [`AutoModelForCausalLM`] 클래스에 전달하십시오.
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+peft_model_id = "ybelkada/opt-350m-lora"
+model = AutoModelForCausalLM.from_pretrained(peft_model_id)
+```
+
+
+
+`AutoModelFor` 클래스나 기본 모델 클래스(예: `OPTForCausalLM` 또는 `LlamaForCausalLM`) 중 하나를 사용하여 PEFT 어댑터를 가져올 수 있습니다.
+
+
+
+`load_adapter` 메소드를 호출하여 PEFT 어댑터를 가져올 수도 있습니다.
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "facebook/opt-350m"
+peft_model_id = "ybelkada/opt-350m-lora"
+
+model = AutoModelForCausalLM.from_pretrained(model_id)
+model.load_adapter(peft_model_id)
+```
+
+## 8비트 또는 4비트로 가져오기 [[load-in-8bit-or-4bit]]
+
+`bitsandbytes` 통합은 8비트와 4비트 정밀도 데이터 유형을 지원하므로 큰 모델을 가져올 때 유용하면서 메모리도 절약합니다. 모델을 하드웨어에 효과적으로 분배하려면 [`~PreTrainedModel.from_pretrained`]에 `load_in_8bit` 또는 `load_in_4bit` 매개변수를 추가하고 `device_map="auto"`를 설정하세요:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+peft_model_id = "ybelkada/opt-350m-lora"
+model = AutoModelForCausalLM.from_pretrained(peft_model_id, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+
+## 새 어댑터 추가 [[add-a-new-adapter]]
+
+새 어댑터가 현재 어댑터와 동일한 유형인 경우에 한해 기존 어댑터가 있는 모델에 새 어댑터를 추가하려면 [`~peft.PeftModel.add_adapter`]를 사용할 수 있습니다. 예를 들어 모델에 기존 LoRA 어댑터가 연결되어 있는 경우:
+
+```py
+from transformers import AutoModelForCausalLM, OPTForCausalLM, AutoTokenizer
+from peft import PeftConfig
+
+model_id = "facebook/opt-350m"
+model = AutoModelForCausalLM.from_pretrained(model_id)
+
+lora_config = LoraConfig(
+ target_modules=["q_proj", "k_proj"],
+ init_lora_weights=False
+)
+
+model.add_adapter(lora_config, adapter_name="adapter_1")
+```
+
+새 어댑터를 추가하려면:
+
+```py
+# attach new adapter with same config
+model.add_adapter(lora_config, adapter_name="adapter_2")
+```
+
+이제 [`~peft.PeftModel.set_adapter`]를 사용하여 어댑터를 사용할 어댑터로 설정할 수 있습니다:
+
+```py
+# use adapter_1
+model.set_adapter("adapter_1")
+output = model.generate(**inputs)
+print(tokenizer.decode(output_disabled[0], skip_special_tokens=True))
+
+# use adapter_2
+model.set_adapter("adapter_2")
+output_enabled = model.generate(**inputs)
+print(tokenizer.decode(output_enabled[0], skip_special_tokens=True))
+```
+
+## 어댑터 활성화 및 비활성화 [[enable-and-disable-adapters]]
+
+모델에 어댑터를 추가한 후 어댑터 모듈을 활성화 또는 비활성화할 수 있습니다. 어댑터 모듈을 활성화하려면:
+
+```py
+from transformers import AutoModelForCausalLM, OPTForCausalLM, AutoTokenizer
+from peft import PeftConfig
+
+model_id = "facebook/opt-350m"
+adapter_model_id = "ybelkada/opt-350m-lora"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+text = "Hello"
+inputs = tokenizer(text, return_tensors="pt")
+
+model = AutoModelForCausalLM.from_pretrained(model_id)
+peft_config = PeftConfig.from_pretrained(adapter_model_id)
+
+# to initiate with random weights
+peft_config.init_lora_weights = False
+
+model.add_adapter(peft_config)
+model.enable_adapters()
+output = model.generate(**inputs)
+```
+
+어댑터 모듈을 비활성화하려면:
+
+```py
+model.disable_adapters()
+output = model.generate(**inputs)
+```
+
+## PEFT 어댑터 훈련 [[train-a-peft-adapter]]
+
+PEFT 어댑터는 [`Trainer`] 클래스에서 지원되므로 특정 사용 사례에 맞게 어댑터를 훈련할 수 있습니다. 몇 줄의 코드를 추가하기만 하면 됩니다. 예를 들어 LoRA 어댑터를 훈련하려면:
+
+
+
+[`Trainer`]를 사용하여 모델을 미세 조정하는 것이 익숙하지 않다면 [사전훈련된 모델을 미세 조정하기](training) 튜토리얼을 확인하세요.
+
+
+
+1. 작업 유형 및 하이퍼파라미터를 지정하여 어댑터 구성을 정의합니다. 하이퍼파라미터에 대한 자세한 내용은 [`~peft.LoraConfig`]를 참조하세요.
+
+```py
+from peft import LoraConfig
+
+peft_config = LoraConfig(
+ lora_alpha=16,
+ lora_dropout=0.1,
+ r=64,
+ bias="none",
+ task_type="CAUSAL_LM",
+)
+```
+
+2. 모델에 어댑터를 추가합니다.
+
+```py
+model.add_adapter(peft_config)
+```
+
+3. 이제 모델을 [`Trainer`]에 전달할 수 있습니다!
+
+```py
+trainer = Trainer(model=model, ...)
+trainer.train()
+```
+
+훈련한 어댑터를 저장하고 다시 가져오려면:
+
+```py
+model.save_pretrained(save_dir)
+model = AutoModelForCausalLM.from_pretrained(save_dir)
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_hardware.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_hardware.md
new file mode 100644
index 0000000000000000000000000000000000000000..01282a0c711147318121f71e07e1a638549906cc
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_hardware.md
@@ -0,0 +1,156 @@
+
+
+
+# 훈련용 사용자 맞춤형 하드웨어 [[custom-hardware-for-training]]
+
+모델 훈련과 추론에 사용하는 하드웨어는 성능에 큰 영향을 미칠 수 있습니다. GPU에 대해 자세히 알아보려면, Tim Dettmer의 훌륭한 블로그 포스트를 확인해보세요. [블로그 포스트 링크](https://timdettmers.com/2020/09/07/which-gpu-for-deep-learning/) (영어로 작성됨).
+
+GPU 설정에 대한 실용적인 조언을 살펴보겠습니다.
+
+## GPU [[gpu]]
+더 큰 모델을 훈련시킬 때는 기본적으로 세 가지 옵션이 있습니다:
+
+- 더 큰 GPU
+- 더 많은 GPU
+- 더 많은 CPU 및 NVMe ([DeepSpeed-Infinity](../en/main_classes/deepspeed#nvme-support)를 통한 오프로드(offload))
+
+우선, 하나의 GPU만 사용하는 경우부터 시작해봅시다.
+
+### 전원 공급과 냉각 [[power-and-cooling]]
+
+비싼 고성능 GPU를 구매한 경우, 올바른 전원 공급과 충분한 냉각을 제공해야 합니다.
+
+**전원 공급**:
+
+일부 고성능 소비자용 GPU는 2개 혹은 가끔가다 3개의 PCI-E 8핀 전원 소켓이 있습니다. 카드에 있는 소켓 수만큼 독립적인 12V PCI-E 8핀 케이블이 연결되어 있는지 확인하세요. 같은 케이블의 한쪽 끝에 있는 2개의 스플릿(또는 피그테일(pigtail) 케이블)을 사용하지 마세요. 즉, GPU에 2개의 소켓이 있다면, PSU(전원 공급 장치)에서 카드로 연결되는 2개의 PCI-E 8핀 케이블이 필요하며, 끝에 2개의 PCI-E 8핀 커넥터가 있는 케이블이 필요하지 않습니다! 그렇지 않으면 카드의 전체 성능을 제대로 발휘하지 못할 수 있습니다.
+
+각각의 PCI-E 8핀 전원 케이블은 PSU 쪽의 12V 레일에 연결되어야 하며 최대 150W의 전력을 공급할 수 있습니다.
+
+일부 다른 GPU는 PCI-E 12핀 커넥터를 사용하며, 이러한 커넥터는 최대 500W-600W의 전력을 공급할 수 있습니다.
+
+저가형 GPU는 6핀 커넥터를 사용하며, 최대 75W의 전력을 공급합니다.
+
+또한 GPU가 안정적인 전압을 받을 수 있도록 고급 PSU를 선택해야 합니다. 일부 저품질의 PSU는 GPU가 최고 성능으로 동작하기 위해 필요한 전압을 안정적으로 공급하지 못할 수 있습니다.
+
+물론, PSU는 GPU에 전원을 공급하기에 충분한 여분의 전력 용량을 가져야 합니다.
+
+**냉각**:
+
+GPU가 과열되면 성능이 저하되고 최대 성능을 발휘하지 못할 수 있으며, 너무 뜨거워지면 중지될 수 있습니다.
+
+GPU가 과열될 때 정확한 적정 온도를 알기 어려우나, 아마도 +80℃ 미만이면 좋지만 더 낮을수록 좋습니다. 70℃-75℃ 정도가 훌륭한 온도 범위입니다. 성능 저하가 발생하기 시작하는 온도는 대략 84℃-90℃ 정도일 것입니다. 하지만 성능 저하 이외에도 지속적으로 매우 높은 온도는 GPU 수명을 단축시킬 수 있습니다.
+
+이어서, 여러 개의 GPU를 사용할 때 가장 중요한 측면 중 하나인 GPU 간 연결 방식을 살펴보겠습니다.
+
+### 다중 GPU 연결 방식 [[multigpu-connectivity]]
+
+다중 GPU를 사용하는 경우 GPU 간의 연결 방식은 전체 훈련 시간에 큰 영향을 미칠 수 있습니다. 만약 GPU가 동일한 물리적 노드에 있을 경우, 다음과 같이 확인할 수 있습니다:
+
+```bash
+nvidia-smi topo -m
+```
+
+만약 NVLink로 연결된 듀얼 GPU 환경이라면, 다음과 같은 결과를 확인할 수 있습니다:
+
+```
+ GPU0 GPU1 CPU Affinity NUMA Affinity
+GPU0 X NV2 0-23 N/A
+GPU1 NV2 X 0-23 N/A
+```
+
+NVLink를 지원하지 않는 다른 환경의 경우에는 다음과 같은 결과를 확인할 수 있습니다:
+```
+ GPU0 GPU1 CPU Affinity NUMA Affinity
+GPU0 X PHB 0-11 N/A
+GPU1 PHB X 0-11 N/A
+```
+
+이 결과에는 다음과 같은 범례가 포함되어 있습니다:
+
+```
+ X = Self
+ SYS = Connection traversing PCIe as well as the SMP interconnect between NUMA nodes (e.g., QPI/UPI)
+ NODE = Connection traversing PCIe as well as the interconnect between PCIe Host Bridges within a NUMA node
+ PHB = Connection traversing PCIe as well as a PCIe Host Bridge (typically the CPU)
+ PXB = Connection traversing multiple PCIe bridges (without traversing the PCIe Host Bridge)
+ PIX = Connection traversing at most a single PCIe bridge
+ NV# = Connection traversing a bonded set of # NVLinks
+```
+
+따라서 첫 번째 결과의 `NV2`는 GPU가 2개의 NVLink로 연결되어 있다는 것을 나타내고, 두 번째 결과의 `PHB`는 일반적인 소비자용 PCIe+브릿지 설정을 가지고 있다는 것을 나타냅니다.
+
+설정에서 어떤 유형의 연결 방식을 가지고 있는지 확인하세요. 일부 연결 방식은 GPU 간 통신을 더 빠르게 만들 수 있으며(NVLink와 같이), 어떤 연결 방식은 더 느리게 만들 수 있습니다(PHB와 같이).
+
+사용하는 확장성 솔루션의 종류에 따라 연결 속도가 주요한 영향을 미칠 수도 있고 미미한 영향을 미칠 수도 있습니다. DDP와 같이 GPU가 거의 동기화하지 않아도 되는 경우, 연결 속도가 느려도 큰 영향을 받지 않습니다. 반면 ZeRO-DP와 같이 GPU간 통신이 많이 필요한 경우, 더 빠른 훈련을 위해서는 더 빠른 연결 속도가 중요합니다.
+
+#### NVLink [[nvlink]]
+
+[NVLink](https://en.wikipedia.org/wiki/NVLink)는 Nvidia에서 개발한 유선 기반의 직렬 다중 레인 근거리 통신 링크입니다.
+
+새로운 세대의 NVLink는 더 빠른 대역폭을 제공합니다. [Nvidia Ampere GA102 GPU Architecture](https://www.nvidia.com/content/dam/en-zz/Solutions/geforce/ampere/pdf/NVIDIA-ampere-GA102-GPU-Architecture-Whitepaper-V1.pdf)에서 아래와 같은 정보를 확인하실 수 있습니다:
+
+> 3세대 NVLink®
+> GA102 GPU는 4개의 x4 링크를 포함하는 NVIDIA의 3세대 NVLink 인터페이스를 활용하며,
+> 각 링크는 두 개의 GPU 간에 각 방향으로 초당 14.0625GB의 대역폭을 제공합니다.
+> 4개의 링크는 각 방향에 초당 56.25GB의 대역폭을 제공하며, 두 개의 GPU 간에는 초당 112.5GB의 총 대역폭을 제공합니다.
+> 두 개의 RTX 3090 GPU를 NVLink를 사용해 SLI로 연결할 수 있습니다.
+> (3-Way 및 4-Way SLI 구성은 지원되지 않음에 유의하세요.)
+
+
+따라서 `nvidia-smi topo -m`의 결과에서 `NVX`의 값이 높을수록 더 좋습니다. 세대는 GPU 아키텍처에 따라 다를 수 있습니다.
+
+그렇다면, openai-community/gpt2를 작은 wikitext 샘플로 학습시키는 예제를 통해, NVLink가 훈련에 어떤 영향을 미치는지 살펴보겠습니다.
+
+결과는 다음과 같습니다:
+
+
+| NVlink | Time |
+| ----- | ---: |
+| Y | 101s |
+| N | 131s |
+
+
+NVLink 사용 시 훈련이 약 23% 더 빠르게 완료됨을 확인할 수 있습니다. 두 번째 벤치마크에서는 `NCCL_P2P_DISABLE=1`을 사용하여 NVLink를 사용하지 않도록 설정했습니다.
+
+전체 벤치마크 코드와 결과는 다음과 같습니다:
+
+```bash
+# DDP w/ NVLink
+
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 torchrun \
+--nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py --model_name_or_path openai-community/gpt2 \
+--dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 --do_train \
+--output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 101.9003, 'train_samples_per_second': 1.963, 'epoch': 0.69}
+
+# DDP w/o NVLink
+
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 NCCL_P2P_DISABLE=1 torchrun \
+--nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py --model_name_or_path openai-community/gpt2 \
+--dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 --do_train
+--output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 131.4367, 'train_samples_per_second': 1.522, 'epoch': 0.69}
+```
+
+하드웨어: 각각 2개의 TITAN RTX 24GB + 2개의 NVLink (`NV2` in `nvidia-smi topo -m`)
+소프트웨어: `pytorch-1.8-to-be` + `cuda-11.0` / `transformers==4.3.0.dev0`
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_infer_cpu.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_infer_cpu.md
new file mode 100644
index 0000000000000000000000000000000000000000..123e56b4f32c2fdf6d90f7e127c74a0a3803d5ea
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_infer_cpu.md
@@ -0,0 +1,73 @@
+
+
+# CPU에서 효율적인 추론하기 [[efficient-inference-on-cpu]]
+
+이 가이드는 CPU에서 대규모 모델을 효율적으로 추론하는 방법에 중점을 두고 있습니다.
+
+## 더 빠른 추론을 위한 `BetterTransformer` [[bettertransformer-for-faster-inference]]
+
+우리는 최근 CPU에서 텍스트, 이미지 및 오디오 모델의 빠른 추론을 위해 `BetterTransformer`를 통합했습니다. 이 통합에 대한 더 자세한 내용은 [이 문서](https://huggingface.co/docs/optimum/bettertransformer/overview)를 참조하세요.
+
+## PyTorch JIT 모드 (TorchScript) [[pytorch-jitmode-torchscript]]
+TorchScript는 PyTorch 코드에서 직렬화와 최적화가 가능한 모델을 생성할때 쓰입니다. TorchScript로 만들어진 프로그램은 기존 Python 프로세스에서 저장한 뒤, 종속성이 없는 새로운 프로세스로 가져올 수 있습니다. PyTorch의 기본 설정인 `eager` 모드와 비교했을때, `jit` 모드는 연산자 결합과 같은 최적화 방법론을 통해 모델 추론에서 대부분 더 나은 성능을 제공합니다.
+
+TorchScript에 대한 친절한 소개는 [PyTorch TorchScript 튜토리얼](https://pytorch.org/tutorials/beginner/Intro_to_TorchScript_tutorial.html#tracing-modules)을 참조하세요.
+
+### JIT 모드와 함께하는 IPEX 그래프 최적화 [[ipex-graph-optimization-with-jitmode]]
+Intel® Extension for PyTorch(IPEX)는 Transformers 계열 모델의 jit 모드에서 추가적인 최적화를 제공합니다. jit 모드와 더불어 Intel® Extension for PyTorch(IPEX)를 활용하시길 강력히 권장드립니다. Transformers 모델에서 자주 사용되는 일부 연산자 패턴은 이미 jit 모드 연산자 결합(operator fusion)의 형태로 Intel® Extension for PyTorch(IPEX)에서 지원되고 있습니다. Multi-head-attention, Concat Linear, Linear+Add, Linear+Gelu, Add+LayerNorm 결합 패턴 등이 이용 가능하며 활용했을 때 성능이 우수합니다. 연산자 결합의 이점은 사용자에게 고스란히 전달됩니다. 분석에 따르면, 질의 응답, 텍스트 분류 및 토큰 분류와 같은 가장 인기 있는 NLP 태스크 중 약 70%가 이러한 결합 패턴을 사용하여 Float32 정밀도와 BFloat16 혼합 정밀도 모두에서 성능상의 이점을 얻을 수 있습니다.
+
+[IPEX 그래프 최적화](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/features/graph_optimization.html)에 대한 자세한 정보를 확인하세요.
+
+#### IPEX 설치: [[ipex-installation]]
+
+IPEX 배포 주기는 PyTorch를 따라서 이루어집니다. 자세한 정보는 [IPEX 설치 방법](https://intel.github.io/intel-extension-for-pytorch/)을 확인하세요.
+
+### JIT 모드 사용법 [[usage-of-jitmode]]
+평가 또는 예측을 위해 Trainer에서 JIT 모드를 사용하려면 Trainer의 명령 인수에 `jit_mode_eval`을 추가해야 합니다.
+
+
+
+PyTorch의 버전이 1.14.0 이상이라면, jit 모드는 jit.trace에서 dict 입력이 지원되므로, 모든 모델의 예측과 평가가 개선될 수 있습니다.
+
+PyTorch의 버전이 1.14.0 미만이라면, 질의 응답 모델과 같이 forward 매개변수의 순서가 jit.trace의 튜플 입력 순서와 일치하는 모델에 득이 될 수 있습니다. 텍스트 분류 모델과 같이 forward 매개변수 순서가 jit.trace의 튜플 입력 순서와 다른 경우, jit.trace가 실패하며 예외가 발생합니다. 이때 예외상황을 사용자에게 알리기 위해 Logging이 사용됩니다.
+
+
+
+[Transformers 질의 응답](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)의 사용 사례 예시를 참조하세요.
+
+
+- CPU에서 jit 모드를 사용한 추론:
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_infer_gpu_one.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_infer_gpu_one.md
new file mode 100644
index 0000000000000000000000000000000000000000..d6ddca6cd039cb54e6b3d273a7336f6a4e73ac8c
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_infer_gpu_one.md
@@ -0,0 +1,184 @@
+
+
+# 단일 GPU에서 효율적인 추론 [[efficient-inference-on-a-single-gpu]]
+
+이 가이드 외에도, [단일 GPU에서의 훈련 가이드](perf_train_gpu_one)와 [CPU에서의 추론 가이드](perf_infer_cpu)에서도 관련 정보를 찾을 수 있습니다.
+
+## Better Transformer: PyTorch 네이티브 Transformer 패스트패스 [[better-transformer-pytorchnative-transformer-fastpath]]
+
+PyTorch 네이티브 [`nn.MultiHeadAttention`](https://pytorch.org/blog/a-better-transformer-for-fast-transformer-encoder-inference/) 어텐션 패스트패스인 BetterTransformer는 [🤗 Optimum 라이브러리](https://huggingface.co/docs/optimum/bettertransformer/overview)의 통합을 통해 Transformers와 함께 사용할 수 있습니다.
+
+PyTorch의 어텐션 패스트패스는 커널 퓨전과 [중첩된 텐서](https://pytorch.org/docs/stable/nested.html)의 사용을 통해 추론 속도를 높일 수 있습니다. 자세한 벤치마크는 [이 블로그 글](https://medium.com/pytorch/bettertransformer-out-of-the-box-performance-for-huggingface-transformers-3fbe27d50ab2)에서 확인할 수 있습니다.
+
+[`optimum`](https://github.com/huggingface/optimum) 패키지를 설치한 후에는 추론 중 Better Transformer를 사용할 수 있도록 [`~PreTrainedModel.to_bettertransformer`]를 호출하여 관련 내부 모듈을 대체합니다:
+
+```python
+model = model.to_bettertransformer()
+```
+
+[`~PreTrainedModel.reverse_bettertransformer`] 메소드는 정규화된 transformers 모델링을 사용하기 위해 모델을 저장하기 전 원래의 모델링으로 돌아갈 수 있도록 해줍니다:
+
+```python
+model = model.reverse_bettertransformer()
+model.save_pretrained("saved_model")
+```
+
+PyTorch 2.0부터는 어텐션 패스트패스가 인코더와 디코더 모두에서 지원됩니다. 지원되는 아키텍처 목록은 [여기](https://huggingface.co/docs/optimum/bettertransformer/overview#supported-models)에서 확인할 수 있습니다.
+
+## FP4 혼합 정밀도 추론을 위한 `bitsandbytes` 통합 [[bitsandbytes-integration-for-fp4-mixedprecision-inference]]
+
+`bitsandbytes`를 설치하면 GPU에서 손쉽게 모델을 압축할 수 있습니다. FP4 양자화를 사용하면 원래의 전체 정밀도 버전과 비교하여 모델 크기를 최대 8배 줄일 수 있습니다. 아래에서 시작하는 방법을 확인하세요.
+
+
+
+이 기능은 다중 GPU 설정에서도 사용할 수 있습니다.
+
+
+
+### 요구 사항 [[requirements-for-fp4-mixedprecision-inference]]
+
+- 최신 `bitsandbytes` 라이브러리
+`pip install bitsandbytes>=0.39.0`
+
+- 최신 `accelerate`를 소스에서 설치
+`pip install git+https://github.com/huggingface/accelerate.git`
+
+- 최신 `transformers`를 소스에서 설치
+`pip install git+https://github.com/huggingface/transformers.git`
+
+### FP4 모델 실행 - 단일 GPU 설정 - 빠른 시작 [[running-fp4-models-single-gpu-setup-quickstart]]
+
+다음 코드를 실행하여 단일 GPU에서 빠르게 FP4 모델을 실행할 수 있습니다.
+
+```py
+from transformers import AutoModelForCausalLM
+
+model_name = "bigscience/bloom-2b5"
+model_4bit = AutoModelForCausalLM.from_pretrained(model_name, device_map="auto", load_in_4bit=True)
+```
+`device_map`은 선택 사항입니다. 그러나 `device_map = 'auto'`로 설정하는 것이 사용 가능한 리소스를 효율적으로 디스패치하기 때문에 추론에 있어 권장됩니다.
+
+### FP4 모델 실행 - 다중 GPU 설정 [[running-fp4-models-multi-gpu-setup]]
+
+다중 GPU에서 혼합 4비트 모델을 가져오는 방법은 단일 GPU 설정과 동일합니다(동일한 명령어 사용):
+```py
+model_name = "bigscience/bloom-2b5"
+model_4bit = AutoModelForCausalLM.from_pretrained(model_name, device_map="auto", load_in_4bit=True)
+```
+하지만 `accelerate`를 사용하여 각 GPU에 할당할 GPU RAM을 제어할 수 있습니다. 다음과 같이 `max_memory` 인수를 사용하세요:
+
+```py
+max_memory_mapping = {0: "600MB", 1: "1GB"}
+model_name = "bigscience/bloom-3b"
+model_4bit = AutoModelForCausalLM.from_pretrained(
+ model_name, device_map="auto", load_in_4bit=True, max_memory=max_memory_mapping
+)
+```
+이 예에서는 첫 번째 GPU가 600MB의 메모리를 사용하고 두 번째 GPU가 1GB를 사용합니다.
+
+### 고급 사용법 [[advanced-usage]]
+
+이 방법의 더 고급 사용법에 대해서는 [양자화](main_classes/quantization) 문서 페이지를 참조하세요.
+
+## Int8 혼합 정밀도 행렬 분해를 위한 `bitsandbytes` 통합 [[bitsandbytes-integration-for-int8-mixedprecision-matrix-decomposition]]
+
+
+
+이 기능은 다중 GPU 설정에서도 사용할 수 있습니다.
+
+
+
+[`LLM.int8() : 8-bit Matrix Multiplication for Transformers at Scale`](https://arxiv.org/abs/2208.07339) 논문에서 우리는 몇 줄의 코드로 Hub의 모든 모델에 대한 Hugging Face 통합을 지원합니다.
+이 방법은 `float16` 및 `bfloat16` 가중치에 대해 `nn.Linear` 크기를 2배로 줄이고, `float32` 가중치에 대해 4배로 줄입니다. 이는 절반 정밀도에서 이상치를 처리함으로써 품질에 거의 영향을 미치지 않습니다.
+
+
+
+Int8 혼합 정밀도 행렬 분해는 행렬 곱셈을 두 개의 스트림으로 분리합니다: (1) fp16로 곱해지는 체계적인 특이값 이상치 스트림 행렬(0.01%) 및 (2) int8 행렬 곱셈의 일반적인 스트림(99.9%). 이 방법을 사용하면 매우 큰 모델에 대해 예측 저하 없이 int8 추론이 가능합니다.
+이 방법에 대한 자세한 내용은 [논문](https://arxiv.org/abs/2208.07339)이나 [통합에 관한 블로그 글](https://huggingface.co/blog/hf-bitsandbytes-integration)에서 확인할 수 있습니다.
+
+
+
+커널은 GPU 전용으로 컴파일되어 있기 때문에 혼합 8비트 모델을 실행하려면 GPU가 필요합니다. 이 기능을 사용하기 전에 모델의 1/4(또는 모델 가중치가 절반 정밀도인 경우 절반)을 저장할 충분한 GPU 메모리가 있는지 확인하세요.
+이 모듈을 사용하는 데 도움이 되는 몇 가지 참고 사항이 아래에 나와 있습니다. 또는 [Google colab](#colab-demos)에서 데모를 따라할 수도 있습니다.
+
+### 요구 사항 [[requirements-for-int8-mixedprecision-matrix-decomposition]]
+
+- `bitsandbytes<0.37.0`을 사용하는 경우, 8비트 텐서 코어(Turing, Ampere 또는 이후 아키텍처 - 예: T4, RTX20s RTX30s, A40-A100)를 지원하는 NVIDIA GPU에서 실행하는지 확인하세요. `bitsandbytes>=0.37.0`을 사용하는 경우, 모든 GPU가 지원됩니다.
+- 올바른 버전의 `bitsandbytes`를 다음 명령으로 설치하세요:
+`pip install bitsandbytes>=0.31.5`
+- `accelerate`를 설치하세요
+`pip install accelerate>=0.12.0`
+
+### 혼합 Int8 모델 실행 - 단일 GPU 설정 [[running-mixedint8-models-single-gpu-setup]]
+
+필요한 라이브러리를 설치한 후 혼합 8비트 모델을 가져오는 방법은 다음과 같습니다:
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+model_name = "bigscience/bloom-2b5"
+model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+
+텍스트 생성의 경우:
+
+* `pipeline()` 함수 대신 모델의 `generate()` 메소드를 사용하는 것을 권장합니다. `pipeline()` 함수로는 추론이 가능하지만, 혼합 8비트 모델에 최적화되지 않았기 때문에 `generate()` 메소드를 사용하는 것보다 느릴 수 있습니다. 또한, nucleus 샘플링과 같은 일부 샘플링 전략은 혼합 8비트 모델에 대해 `pipeline()` 함수에서 지원되지 않습니다.
+* 입력을 모델과 동일한 GPU에 배치하는 것이 좋습니다.
+
+다음은 간단한 예입니다:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model_name = "bigscience/bloom-2b5"
+tokenizer = AutoTokenizer.from_pretrained(model_name)
+model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+
+prompt = "Hello, my llama is cute"
+inputs = tokenizer(prompt, return_tensors="pt").to("cuda")
+generated_ids = model.generate(**inputs)
+outputs = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+```
+
+
+### 혼합 Int8 모델 실행 - 다중 GPU 설정 [[running-mixedint8-models-multi-gpu-setup]]
+
+다중 GPU에서 혼합 8비트 모델을 로드하는 방법은 단일 GPU 설정과 동일합니다(동일한 명령어 사용):
+```py
+model_name = "bigscience/bloom-2b5"
+model_8bit = AutoModelForCausalLM.from_pretrained(model_name, quantization_config=BitsAndBytesConfig(load_in_8bit=True))
+```
+하지만 `accelerate`를 사용하여 각 GPU에 할당할 GPU RAM을 제어할 수 있습니다. 다음과 같이 `max_memory` 인수를 사용하세요:
+
+```py
+max_memory_mapping = {0: "1GB", 1: "2GB"}
+model_name = "bigscience/bloom-3b"
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ model_name, device_map="auto", load_in_8bit=True, max_memory=max_memory_mapping
+)
+```
+이 예시에서는 첫 번째 GPU가 1GB의 메모리를 사용하고 두 번째 GPU가 2GB를 사용합니다.
+
+### Colab 데모 [[colab-demos]]
+
+이 방법을 사용하면 이전에 Google Colab에서 추론할 수 없었던 모델에 대해 추론할 수 있습니다.
+Google Colab에서 8비트 양자화를 사용하여 T5-11b(42GB in fp32)를 실행하는 데모를 확인하세요:
+
+[](https://colab.research.google.com/drive/1YORPWx4okIHXnjW7MSAidXN29mPVNT7F?usp=sharing)
+
+또는 BLOOM-3B에 대한 데모를 확인하세요:
+
+[](https://colab.research.google.com/drive/1qOjXfQIAULfKvZqwCen8-MoWKGdSatZ4?usp=sharing)
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_cpu.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_cpu.md
new file mode 100644
index 0000000000000000000000000000000000000000..1a6c58b25afae10db053e7ae94b7f5c36c75fb7a
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_cpu.md
@@ -0,0 +1,67 @@
+
+
+# CPU에서 효율적인 훈련 [[efficient-training-on-cpu]]
+
+이 가이드는 CPU에서 대규모 모델을 효율적으로 훈련하는 데 초점을 맞춥니다.
+
+## IPEX와 혼합 정밀도 [[mixed-precision-with-ipex]]
+
+IPEX는 AVX-512 이상을 지원하는 CPU에 최적화되어 있으며, AVX2만 지원하는 CPU에도 기능적으로 작동합니다. 따라서 AVX-512 이상의 Intel CPU 세대에서는 성능상 이점이 있을 것으로 예상되지만, AVX2만 지원하는 CPU (예: AMD CPU 또는 오래된 Intel CPU)의 경우에는 IPEX 아래에서 더 나은 성능을 보일 수 있지만 이는 보장되지 않습니다. IPEX는 Float32와 BFloat16를 모두 사용하여 CPU 훈련을 위한 성능 최적화를 제공합니다. BFloat16의 사용은 다음 섹션의 주요 초점입니다.
+
+저정밀도 데이터 타입인 BFloat16은 3세대 Xeon® Scalable 프로세서 (코드명: Cooper Lake)에서 AVX512 명령어 집합을 네이티브로 지원해 왔으며, 다음 세대의 Intel® Xeon® Scalable 프로세서에서 Intel® Advanced Matrix Extensions (Intel® AMX) 명령어 집합을 지원하여 성능을 크게 향상시킬 예정입니다. CPU 백엔드의 자동 혼합 정밀도 기능은 PyTorch-1.10부터 활성화되었습니다. 동시에, Intel® Extension for PyTorch에서 BFloat16에 대한 CPU의 자동 혼합 정밀도 및 연산자의 BFloat16 최적화를 대규모로 활성화하고, PyTorch 마스터 브랜치로 부분적으로 업스트림을 반영했습니다. 사용자들은 IPEX 자동 혼합 정밀도를 사용하여 더 나은 성능과 사용자 경험을 얻을 수 있습니다.
+
+[자동 혼합 정밀도](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/features/amp.html)에 대한 자세한 정보를 확인하십시오.
+
+### IPEX 설치: [[ipex-installation]]
+
+IPEX 릴리스는 PyTorch를 따라갑니다. pip를 통해 설치하려면:
+
+| PyTorch Version | IPEX version |
+| :---------------: | :----------: |
+| 1.13 | 1.13.0+cpu |
+| 1.12 | 1.12.300+cpu |
+| 1.11 | 1.11.200+cpu |
+| 1.10 | 1.10.100+cpu |
+
+```bash
+pip install intel_extension_for_pytorch== -f https://developer.intel.com/ipex-whl-stable-cpu
+```
+
+[IPEX 설치](https://intel.github.io/intel-extension-for-pytorch/cpu/latest/tutorials/installation.html)에 대한 더 많은 접근 방법을 확인하십시오.
+
+### Trainer에서의 사용법 [[usage-in-trainer]]
+Trainer에서 IPEX의 자동 혼합 정밀도를 활성화하려면 사용자는 훈련 명령 인수에 `use_ipex`, `bf16`, `no_cuda`를 추가해야 합니다.
+
+[Transformers 질문-응답](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)의 사용 사례를 살펴보겠습니다.
+
+- CPU에서 BF16 자동 혼합 정밀도를 사용하여 IPEX로 훈련하기:
+
+
+### 실습 예시 [[practice-example]]
+
+블로그: [Intel Sapphire Rapids로 PyTorch Transformers 가속화](https://huggingface.co/blog/intel-sapphire-rapids)
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_cpu_many.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_cpu_many.md
new file mode 100644
index 0000000000000000000000000000000000000000..e7a68971a7dc54e465dfbefb3290a5a46daf0524
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_cpu_many.md
@@ -0,0 +1,134 @@
+
+
+# 다중 CPU에서 효율적으로 훈련하기 [[efficient-training-on-multiple-cpus]]
+
+하나의 CPU에서 훈련하는 것이 너무 느릴 때는 다중 CPU를 사용할 수 있습니다. 이 가이드는 PyTorch 기반의 DDP를 사용하여 분산 CPU 훈련을 효율적으로 수행하는 방법에 대해 설명합니다.
+
+## PyTorch용 Intel® oneCCL 바인딩 [[intel-oneccl-bindings-for-pytorch]]
+
+[Intel® oneCCL](https://github.com/oneapi-src/oneCCL) (collective communications library)은 allreduce, allgather, alltoall과 같은 집합 통신(collective communications)을 구현한 효율적인 분산 딥러닝 훈련을 위한 라이브러리입니다. oneCCL에 대한 자세한 정보는 [oneCCL 문서](https://spec.oneapi.com/versions/latest/elements/oneCCL/source/index.html)와 [oneCCL 사양](https://spec.oneapi.com/versions/latest/elements/oneCCL/source/index.html)을 참조하세요.
+
+`oneccl_bindings_for_pytorch` 모듈 (`torch_ccl`은 버전 1.12 이전에 사용)은 PyTorch C10D ProcessGroup API를 구현하며, 외부 ProcessGroup로 동적으로 가져올 수 있으며 현재 Linux 플랫폼에서만 작동합니다.
+
+[oneccl_bind_pt](https://github.com/intel/torch-ccl)에서 더 자세한 정보를 확인하세요.
+
+### PyTorch용 Intel® oneCCL 바인딩 설치: [[intel-oneccl-bindings-for-pytorch-installation]]
+
+다음 Python 버전에 대한 Wheel 파일을 사용할 수 있습니다.
+
+| Extension Version | Python 3.6 | Python 3.7 | Python 3.8 | Python 3.9 | Python 3.10 |
+| :---------------: | :--------: | :--------: | :--------: | :--------: | :---------: |
+| 1.13.0 | | √ | √ | √ | √ |
+| 1.12.100 | | √ | √ | √ | √ |
+| 1.12.0 | | √ | √ | √ | √ |
+| 1.11.0 | | √ | √ | √ | √ |
+| 1.10.0 | √ | √ | √ | √ | |
+
+```bash
+pip install oneccl_bind_pt=={pytorch_version} -f https://developer.intel.com/ipex-whl-stable-cpu
+```
+`{pytorch_version}`은 1.13.0과 같이 PyTorch 버전을 나타냅니다.
+[oneccl_bind_pt 설치](https://github.com/intel/torch-ccl)에 대한 더 많은 접근 방법을 확인해 보세요.
+oneCCL과 PyTorch의 버전은 일치해야 합니다.
+
+
+
+oneccl_bindings_for_pytorch 1.12.0 버전의 미리 빌드된 Wheel 파일은 PyTorch 1.12.1과 호환되지 않습니다(PyTorch 1.12.0용입니다).
+PyTorch 1.12.1은 oneccl_bindings_for_pytorch 1.12.10 버전과 함께 사용해야 합니다.
+
+
+
+## Intel® MPI 라이브러리 [[intel-mpi-library]]
+이 표준 기반 MPI 구현을 사용하여 Intel® 아키텍처에서 유연하고 효율적이며 확장 가능한 클러스터 메시징을 제공하세요. 이 구성 요소는 Intel® oneAPI HPC Toolkit의 일부입니다.
+
+oneccl_bindings_for_pytorch는 MPI 도구 세트와 함께 설치됩니다. 사용하기 전에 환경을 소스로 지정해야 합니다.
+
+Intel® oneCCL 버전 1.12.0 이상인 경우
+```bash
+oneccl_bindings_for_pytorch_path=$(python -c "from oneccl_bindings_for_pytorch import cwd; print(cwd)")
+source $oneccl_bindings_for_pytorch_path/env/setvars.sh
+```
+
+Intel® oneCCL 버전이 1.12.0 미만인 경우
+```bash
+torch_ccl_path=$(python -c "import torch; import torch_ccl; import os; print(os.path.abspath(os.path.dirname(torch_ccl.__file__)))")
+source $torch_ccl_path/env/setvars.sh
+```
+
+#### IPEX 설치: [[ipex-installation]]
+
+IPEX는 Float32와 BFloat16을 모두 사용하는 CPU 훈련을 위한 성능 최적화를 제공합니다. [single CPU section](./perf_train_cpu)을 참조하세요.
+
+
+이어서 나오는 "Trainer에서의 사용"은 Intel® MPI 라이브러리의 mpirun을 예로 들었습니다.
+
+
+## Trainer에서의 사용 [[usage-in-trainer]]
+Trainer에서 ccl 백엔드를 사용하여 멀티 CPU 분산 훈련을 활성화하려면 명령 인수에 **`--ddp_backend ccl`**을 추가해야 합니다.
+
+[질의 응답 예제](https://github.com/huggingface/transformers/tree/main/examples/pytorch/question-answering)를 사용한 예를 살펴보겠습니다.
+
+
+다음 명령은 한 Xeon 노드에서 2개의 프로세스로 훈련을 활성화하며, 각 소켓당 하나의 프로세스가 실행됩니다. OMP_NUM_THREADS/CCL_WORKER_COUNT 변수는 최적의 성능을 위해 조정할 수 있습니다.
+```shell script
+ export CCL_WORKER_COUNT=1
+ export MASTER_ADDR=127.0.0.1
+ mpirun -n 2 -genv OMP_NUM_THREADS=23 \
+ python3 run_qa.py \
+ --model_name_or_path google-bert/bert-large-uncased \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --per_device_train_batch_size 12 \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir /tmp/debug_squad/ \
+ --no_cuda \
+ --ddp_backend ccl \
+ --use_ipex
+```
+다음 명령은 두 개의 Xeon(노드0 및 노드1, 주 프로세스로 노드0을 사용)에서 총 4개의 프로세스로 훈련을 활성화하며, 각 소켓당 하나의 프로세스가 실행됩니다. OMP_NUM_THREADS/CCL_WORKER_COUNT 변수는 최적의 성능을 위해 조정할 수 있습니다.
+
+노드0에서는 각 노드의 IP 주소를 포함하는 구성 파일(예: hostfile)을 생성하고 해당 구성 파일 경로를 인수로 전달해야 합니다.
+```shell script
+ cat hostfile
+ xxx.xxx.xxx.xxx #node0 ip
+ xxx.xxx.xxx.xxx #node1 ip
+```
+이제 노드0에서 다음 명령을 실행하면 **4DDP**가 노드0 및 노드1에서 BF16 자동 혼합 정밀도로 활성화됩니다.
+```shell script
+ export CCL_WORKER_COUNT=1
+ export MASTER_ADDR=xxx.xxx.xxx.xxx #node0 ip
+ mpirun -f hostfile -n 4 -ppn 2 \
+ -genv OMP_NUM_THREADS=23 \
+ python3 run_qa.py \
+ --model_name_or_path google-bert/bert-large-uncased \
+ --dataset_name squad \
+ --do_train \
+ --do_eval \
+ --per_device_train_batch_size 12 \
+ --learning_rate 3e-5 \
+ --num_train_epochs 2 \
+ --max_seq_length 384 \
+ --doc_stride 128 \
+ --output_dir /tmp/debug_squad/ \
+ --no_cuda \
+ --ddp_backend ccl \
+ --use_ipex \
+ --bf16
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_gpu_many.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_gpu_many.md
new file mode 100644
index 0000000000000000000000000000000000000000..b8553ea499ef10af4746e50aac6a2362309cdb55
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_gpu_many.md
@@ -0,0 +1,533 @@
+
+
+# 다중 GPU에서 효율적인 훈련 [[efficient-training-on-multiple-gpus]]
+
+단일 GPU에서의 훈련이 너무 느리거나 모델 가중치가 단일 GPU의 메모리에 맞지 않는 경우, 다중-GPU 설정을 사용합니다. 단일 GPU에서 다중 GPU로 전환하기 위해서는 작업을 분산해야 합니다. 데이터, 텐서 또는 파이프라인과 같은 병렬화 기법을 사용하여 작업을 병렬로 처리할 수 있습니다. 그러나 이러한 설정을 모두에게 적용할 수 있는 완벽한 해결책은 없으며, 어떤 설정이 가장 적합한지는 사용하는 하드웨어에 따라 달라집니다. 이 문서는 주로 PyTorch 기반의 구현을 중심으로 설명하며, 대부분의 개념은 다른 프레임워크에도 적용될 수 있을 것으로 예상됩니다.
+
+
+
+ 참고: [단일 GPU 섹션](perf_train_gpu_one)에서 소개된 전략(혼합 정밀도 훈련 또는 그래디언트 누적 등)은 일반적으로 모델 훈련에 적용되며, 다중-GPU 또는 CPU 훈련과 같은 다음 섹션으로 진입하기 전에 해당 섹션을 참고하는 것이 좋습니다.
+
+
+
+먼저 1D 병렬화 기술에 대해 자세히 논의한 후, 이러한 기술을 결합하여 2D 및 3D 병렬화를 구현하여 더 빠른 훈련과 더 큰 모델을 지원하는 방법을 살펴볼 것입니다. 또한 다른 효과적인 대안 방식도 소개될 예정입니다.
+
+## 개념 [[concepts]]
+
+다음은 이 문서에서 자세히 설명될 주요 개념에 대한 간단한 설명입니다.
+
+1. **DataParallel (DP)** - 동일한 설정이 여러 번 복제되고, 각 설정에 데이터 일부를 받습니다. 처리는 병렬로 수행되며 모든 설정은 각 훈련 단계의 끝날 때 동기화됩니다.
+2. **TensorParallel (TP)** - 각 텐서는 여러 개의 묶음으로 분할되기에, 전체 텐서가 단일 GPU에 상주하는 대신 텐서의 각 샤드가 지정된 GPU에 상주합니다. 처리하는 동안 각 샤드는 서로 다른 GPU에서 개별적으로 병렬 처리되며 결과는 단계가 끝날 때 동기화됩니다. 분할이 수평 수준에서 이루어지기 때문에 이를 수평 병렬 처리라고 부를 수 있습니다.
+3. **PipelineParallel (PP)** - 모델이 수직으로 (레이어 수준) 여러 GPU에 분할되어 모델의 단일 GPU에는 하나 또는 여러 레이어가 배치됩니다. 각 GPU는 파이프라인의 서로 다른 단계를 병렬로 처리하며 작은 배치 묶음에서 작동합니다.
+4. **Zero Redundancy Optimizer (ZeRO)** - TP와 유사하게 텐서를 샤딩하지만, 전체 텐서는 순방향 또는 역방향 계산을 위해 재구성되므로 모델을 수정할 필요가 없습니다. 또한 제한된 GPU 메모리를 보완하기 위해 다양한 오프로드 기술을 지원합니다.
+5. **Sharded DDP** - ZeRO의 기본 개념으로 다른 ZeRO 구현에서도 사용되는 용어입니다.
+
+각 개념의 구체적인 내용에 대해 자세히 들어가기 전에 대규모 인프라에서 대규모 모델을 훈련하는 경우의 대략적인 결정 과정을 살펴보겠습니다.
+
+## 확장성 전략 [[scalability-strategy]]
+
+**⇨ 단일 노드 / 다중-GPU**
+* 모델이 단일 GPU에 맞는 경우:
+
+ 1. DDP - 분산 DP
+ 2. ZeRO - 상황과 구성에 따라 더 빠를 수도 있고 그렇지 않을 수도 있음
+
+* 모델이 단일 GPU에 맞지 않는 경우:
+
+ 1. PP
+ 2. ZeRO
+ 3. TP
+
+ 노드 내 연결 속도가 매우 빠른 NVLINK 또는 NVSwitch의 경우 세 가지 방법은 대부분 비슷한 성능을 보여야 하며, PP가 없는 경우 TP 또는 ZeRO보다 빠를 것입니다. TP의 정도도 차이를 만들 수 있습니다. 특정 설정에서 승자를 찾기 위해 실험하는 것이 가장 좋습니다.
+
+ TP는 거의 항상 단일 노드 내에서 사용됩니다. 즉, TP 크기 <= 노드당 GPU 수입니다.
+
+* 가장 큰 레이어가 단일 GPU에 맞지 않는 경우:
+
+ 1. ZeRO를 사용하지 않는 경우 - PP만으로는 맞지 않으므로 TP를 반드시 사용해야 함
+ 2. ZeRO를 사용하는 경우에는 위의 "단일 GPU" 항목과 동일
+
+
+**⇨ 다중 노드 / 다중 GPU**
+
+* 노드 간 연결 속도가 빠른 경우:
+
+ 1. ZeRO - 모델에 대부분의 수정을 필요로 하지 않음
+ 2. PP+TP+DP - 통신이 적지만 모델에 대대적인 변경이 필요함
+
+* 노드 간 연결 속도가 느리며, GPU 메모리가 여전히 부족한 경우:
+
+ 1. DP+PP+TP+ZeRO-1
+
+
+
+## 데이터 병렬화 [[data-parallelism]]
+
+2개의 GPU만으로도 대부분의 사용자들은 `DataParallel` (DP)과 `DistributedDataParallel` (DDP)을 통해 향상된 훈련 속도를 누릴 수 있습니다. 이는 PyTorch의 내장 기능입니다. 일반적으로 DDP를 사용하는 것이 좋으며, DP는 일부 모델에서 작동하지 않을 수 있으므로 주의해야 합니다. [PyTorch 문서](https://pytorch.org/docs/master/generated/torch.nn.DataParallel.html)에서도 DDP의 사용을 권장합니다.
+
+### DP vs DDP [[dp-vs-ddp]]
+
+`DistributedDataParallel` (DDP)은 일반적으로 `DataParallel` (DP)보다 빠르지만, 항상 그렇지는 않습니다:
+* DP는 파이썬 스레드 기반인 반면, DDP는 다중 프로세스 기반이기 때문에 GIL과 같은 파이썬 스레드 제한이 없습니다.
+* 그러나 GPU 카드 간의 느린 상호 연결성은 DDP로 인해 실제로 느린 결과를 낼 수 있습니다.
+
+이 두 모드 간의 GPU 간 통신 오버헤드의 주요 차이점은 다음과 같습니다:
+
+[DDP](https://pytorch.org/docs/master/notes/ddp.html):
+
+- 시작할 때, 주 프로세스가 모델을 gpu 0에서 다른 모든 gpu로 복제합니다.
+- 그런 다음 각 배치에 대해:
+ 1. 각 gpu는 자체 미니 배치 데이터를 직접 사용합니다.
+ 2. `backward` 동안 로컬 그래디언트가 준비되면, 모든 프로세스에 평균화됩니다.
+
+[DP](https://pytorch.org/docs/master/generated/torch.nn.DataParallel.html):
+
+각 배치에 대해:
+ 1. gpu 0은 데이터 배치를 읽고 각 gpu에 미니 배치를 보냅니다.
+ 2. 업데이트된 모델을 gpu 0에서 각 gpu로 복제합니다.
+ 3. `forward`를 실행하고 각 gpu의 출력을 gpu 0으로 보내고 손실을 계산합니다.
+ 4. gpu 0에서 모든 gpu로 손실을 분산하고 `backward`를 실행합니다.
+ 5. 각 gpu에서 그래디언트를 gpu 0으로 보내고 이를 평균화합니다.
+
+DDP는 각 배치마다 그래디언트를 보내는 통신만을 수행하며, DP는 배치마다 5개의 다른 데이터 교환을 수행합니다.
+
+DP는 파이썬 스레드를 통해 프로세스 내에서 데이터를 복제하며, DDP는 [torch.distributed](https://pytorch.org/docs/master/distributed.html)를 통해 데이터를 복제합니다.
+
+DP에서는 gpu 0이 다른 gpu보다 훨씬 더 많은 작업을 수행하므로, gpu의 활용도가 낮아집니다.
+
+DDP는 여러 대의 컴퓨터에서 사용할 수 있지만, DP의 경우는 그렇지 않습니다.
+
+DP와 DDP 사이에는 다른 차이점이 있지만, 이 토론과는 관련이 없습니다.
+
+이 2가지 모드를 깊게 이해하고 싶다면, [이 문서](https://www.telesens.co/2019/04/04/distributed-data-parallel-training-using-pytorch-on-aws/)를 강력히 추천합니다. 이 문서는 멋진 다이어그램을 포함하고 있으며, 다양한 하드웨어에서 여러 벤치마크와 프로파일러 출력을 설명하여 필요한 세부 사항을 모두 설명합니다.
+
+실제 벤치마크를 살펴보겠습니다:
+
+| Type | NVlink | Time |
+| :----- | ----- | ---: |
+| 2:DP | Y | 110s |
+| 2:DDP | Y | 101s |
+| 2:DDP | N | 131s |
+
+
+분석:
+
+여기서 DP는 NVlink가 있는 DDP보다 약 10% 느립니다. 그러나 NVlink가 없는 DDP보다 약 15% 빠릅니다.
+
+실제 차이는 각 GPU가 다른 GPU와 동기화해야 하는 데이터 양에 따라 달라질 것입니다. 동기화할 데이터가 많을수록 느린 링크가 총 실행 시간을 늦출 수 있습니다.
+
+다음은 전체 벤치마크 코드와 출력입니다:
+
+해당 벤치마크에서 `NCCL_P2P_DISABLE=1`을 사용하여 NVLink 기능을 비활성화했습니다.
+
+```bash
+
+# DP
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 \
+python examples/pytorch/language-modeling/run_clm.py \
+--model_name_or_path openai-community/gpt2 --dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 \
+--do_train --output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 110.5948, 'train_samples_per_second': 1.808, 'epoch': 0.69}
+
+# DDP w/ NVlink
+rm -r /tmp/test-clm; CUDA_VISIBLE_DEVICES=0,1 \
+torchrun --nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py \
+--model_name_or_path openai-community/gpt2 --dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 \
+--do_train --output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 101.9003, 'train_samples_per_second': 1.963, 'epoch': 0.69}
+
+# DDP w/o NVlink
+rm -r /tmp/test-clm; NCCL_P2P_DISABLE=1 CUDA_VISIBLE_DEVICES=0,1 \
+torchrun --nproc_per_node 2 examples/pytorch/language-modeling/run_clm.py \
+--model_name_or_path openai-community/gpt2 --dataset_name wikitext --dataset_config_name wikitext-2-raw-v1 \
+--do_train --output_dir /tmp/test-clm --per_device_train_batch_size 4 --max_steps 200
+
+{'train_runtime': 131.4367, 'train_samples_per_second': 1.522, 'epoch': 0.69}
+```
+
+하드웨어: 각각 24GB의 TITAN RTX 2개 + NVlink과 2개의 NVLink (`nvidia-smi topo -m`에서 `NV2`입니다.)
+소프트웨어: `pytorch-1.8-to-be` + `cuda-11.0` / `transformers==4.3.0.dev0`
+
+## ZeRO 데이터 병렬화 [[zero-data-parallelism]]
+
+ZeRO를 기반으로 한 데이터 병렬화 (ZeRO-DP)는 다음 [블로그 글](https://www.microsoft.com/en-us/research/blog/zero-deepspeed-new-system-optimizations-enable-training-models-with-over-100-billion-parameters/)의 다음 다이어그램에서 설명되고 있습니다.
+
+
+이 개념은 이해하기 어려울 수 있지만, 실제로는 매우 간단한 개념입니다. 이는 일반적인 `DataParallel` (DP)과 동일하지만, 전체 모델 매개변수, 그래디언트 및 옵티마이저 상태를 복제하는 대신 각 GPU는 그 중 일부만 저장합니다. 그리고 실행 시간에는 주어진 레이어에 대해 전체 레이어 매개변수가 필요할 때 각 GPU가 서로에게 필요한 부분을 제공하기 위해 동기화됩니다 - 그게 전부입니다.
+
+각각 3개의 레이어와 3개의 매개변수가 있는 간단한 모델을 생각해 봅시다:
+```
+La | Lb | Lc
+---|----|---
+a0 | b0 | c0
+a1 | b1 | c1
+a2 | b2 | c2
+```
+레이어 La에는 가중치 a0, a1 및 a2가 있습니다.
+
+3개의 GPU가 있는 경우, Sharded DDP (= Zero-DP)는 다음과 같이 모델을 3개의 GPU에 분할합니다:
+
+```
+GPU0:
+La | Lb | Lc
+---|----|---
+a0 | b0 | c0
+
+GPU1:
+La | Lb | Lc
+---|----|---
+a1 | b1 | c1
+
+GPU2:
+La | Lb | Lc
+---|----|---
+a2 | b2 | c2
+```
+
+일반적인 DNN 다이어그램을 상상해보면 이는 텐서 병렬 처리와 같은 수평 슬라이싱입니다. 수직 슬라이싱은 전체 레이어 그룹을 다른 GPU에 배치하는 것입니다. 이는 시작에 불과합니다.
+
+이제 이러한 각각의 GPU는 DP에서 작동하는 것과 마찬가지로 일반적인 미니 배치를 받습니다:
+```
+x0 => GPU0
+x1 => GPU1
+x2 => GPU2
+```
+
+입력은 수정되지 않은 상태로 일반 모델에 의해 처리될 것으로 간주합니다.
+
+먼저, 입력은 레이어 La에 도달합니다.
+
+GPU0에만 집중해 보겠습니다. x0은 순방향 경로를 수행하기 위해 a0, a1, a2 파라미터가 필요하지만 GPU0에는 a0만 있습니다. GPU1에서 a1을, GPU2에서 a2를 전송받아 모델의 모든 조각을 하나로 모읍니다.
+
+병렬적으로, GPU1은 미니 배치 x1을 받고 a1만 가지고 있지만, a0 및 a2 매개변수가 필요합니다. 따라서 GPU0 및 GPU2에서 이를 가져옵니다.
+
+GPU2도 동일한 작업을 수행합니다. 입력 x2를 받고 GPU0 및 GPU1에서 각각 a0과 a1을, 그리고 자신의 a2와 함께 전체 텐서를 복원합니다.
+
+3개의 GPU는 복원된 전체 텐서를 받고 forward가 수행됩니다.
+
+계산이 완료되면 더 이상 필요하지 않은 데이터는 삭제되고, 해당 데이터는 계산 중에만 사용됩니다. 복원은 사전 패치를 통해 효율적으로 수행됩니다.
+
+그리고 전체 프로세스는 레이어 Lb에 대해 반복되고, 그 다음 Lc로 순방향으로, 그다음은 역방향으로 Lc -> Lb -> La로 반복됩니다.
+
+개인적으로 이것은 효율적인 그룹 배낭 여행자의 중량 분배 전략처럼 들립니다:
+
+1. 사람 A가 텐트를 운반합니다.
+2. 사람 B가 난로를 운반합니다.
+3. 사람 C가 도끼를 운반합니다.
+
+이제 매일 밤 각자 가진 것을 다른 사람들과 공유하고, 가지지 않은 것은 다른 사람들로부터 받고, 아침에는 할당된 유형의 장비를 싸고 계속해서 여행을 진행합니다. 이것이 Sharded DDP / Zero DP입니다.
+
+이 전략을 각각 자신의 텐트, 난로 및 도끼를 개별적으로 운반해야 하는 단순한 전략과 비교해보면 훨씬 비효율적일 것입니다. 이것이 Pytorch의 DataParallel (DP 및 DDP)입니다.
+
+이 주제에 대해 논문을 읽을 때 다음 동의어를 만날 수 있습니다: Sharded, Partitioned.
+
+ZeRO가 모델 가중치를 분할하는 방식을 자세히 살펴보면, 텐서 병렬화와 매우 유사한 것을 알 수 있습니다. 이는 이후에 설명될 수직 모델 병렬화와는 달리 각 레이어의 가중치를 분할/분할하기 때문입니다.
+
+구현:
+
+- [DeepSpeed](https://www.deepspeed.ai/tutorials/zero/)는 1단계 + 2단계 + 3단계의 ZeRO-DP를 제공합니다.
+- [Fairscale](https://github.com/facebookresearch/fairscale/#optimizer-state-sharding-zero)은 1단계 + 2단계 + 3단계의 ZeRO-DP를 제공합니다.
+- [`transformers` 통합](main_classes/trainer#trainer-integrations)
+
+## 네이티브 모델 병렬 처리(수직적) 및 파이프라인 병렬 처리[[naive-model-parallelism-vertical-and-pipeline-parallelism]]
+
+Naive Model Parallelism (MP)은 모델 레이어 그룹을 다중 GPU에 분산하는 방식입니다. 메커니즘은 상대적으로 간단합니다. 원하는 레이어를 `.to()`를 사용하여 원하는 장치로 전환하면 데이터가 해당 레이어로 들어오고 나갈 때 데이터도 레이어와 동일한 장치로 전환되고 나머지는 수정되지 않습니다.
+
+대부분의 모델이 그려지는 방식이 레이어를 세로로 슬라이스하기 때문에 이를 수직 모델 병렬화라고 부릅니다. 예를 들어 다음 다이어그램은 8레이어 모델을 보여줍니다:
+
+```
+=================== ===================
+| 0 | 1 | 2 | 3 | | 4 | 5 | 6 | 7 |
+=================== ===================
+ gpu0 gpu1
+```
+우리는 모델을 수직으로 2개로 분할하여 레이어 0-3을 GPU0에 배치하고 레이어 4-7을 GPU1에 배치했습니다.
+
+이제 데이터가 레이어 0에서 1로, 1에서 2로, 2에서 3으로 이동하는 동안에는 일반적인 모델입니다. 그러나 데이터가 레이어 3에서 레이어 4로 전달되어야 할 때는 GPU0에서 GPU1로 이동해야 하므로 통신 오버헤드가 발생합니다. 참여하는 GPU가 동일한 컴퓨팅 노드(예: 동일한 물리적인 기계)에 있는 경우 이 복사는 매우 빠릅니다. 그러나 GPU가 서로 다른 컴퓨팅 노드(예: 여러 기계)에 위치한 경우 통신 오버헤드는 상당히 크게 될 수 있습니다.
+
+그런 다음 레이어 4부터 5로, 6으로, 7로 진행되는 것은 일반적인 모델과 동일하게 진행되고, 7번째 레이어가 완료되면 데이터를 다시 레이어 0으로 보내거나 또는 레이블을 마지막 레이어로 보내야 할 필요가 있습니다. 이제 손실을 계산하고 옵티마이저가 작동할 수 있습니다.
+
+문제점:
+- 이 방식을 "naive" MP라고 부르는 이유는 주어진 상황에 하나의 GPU를 제외한 모든 GPU가 유휴 상태라는 점입니다. 따라서 4개의 GPU를 사용하는 경우 단일 GPU의 메모리 양을 4배로 늘리고 나머지 하드웨어는 무시하는 것과 거의 동일합니다. 또한 장치 간 데이터 복사의 오버헤드도 있습니다. 따라서 4개의 6GB 카드는 naive MP를 사용하여 1개의 24GB 카드와 동일한 크기를 수용할 수 있지만, 후자는 데이터 복사의 오버헤드가 없으므로 훈련을 더 빨리 완료합니다. 그러나 예를 들어 40GB 카드가 있고 45GB 모델을 맞추어야 할 경우 4개의 40GB 카드로 맞출 수 있습니다 (하지만 그래디언트와 옵티마이저 상태 때문에 가까스로 가능합니다).
+- 공유 임베딩은 GPU 간에 복사해야 할 수도 있습니다.
+
+파이프라인 병렬화 (PP)은 거의 naive MP와 동일하지만 GPU 유휴 상태 문제를 해결하기 위해 들어오는 배치를 마이크로 배치로 나누고 인공적으로 파이프라인을 생성하여 서로 다른 GPU가 동시에 계산에 참여할 수 있게 합니다.
+
+[GPipe 논문](https://ai.googleblog.com/2019/03/introducing-gpipe-open-source-library.html)에서 가져온 그림은 상단에 naive MP를, 하단에는 PP를 보여줍니다:
+
+
+
+하단 다이어그램에서 PP가 유휴 영역이 적은 것을 쉽게 볼 수 있습니다. 유휴 부분을 "bubble"이라고 합니다.
+
+다이어그램의 양쪽 부분은 참여하는 GPU가 4개인 병렬성을 보여줍니다. 즉, 4개의 GPU가 파이프라인에 참여합니다. 따라서 4개의 파이프 단계 F0, F1, F2 및 F3의 순방향 경로와 B3, B2, B1 및 B0의 역방향 경로가 있습니다.
+
+PP는 조정해야 할 새로운 하이퍼파라미터인 `chunks`를 도입합니다. 이는 동일한 파이프 단계를 통해 일련의 데이터를 묶어서 보내는 방식을 정의합니다. 예를 들어, 아래 다이어그램에서 `chunks=4`를 볼 수 있습니다. GPU0은 0, 1, 2 및 3 (F0,0, F0,1, F0,2, F0,3) 묶음에서 동일한 순방향 경로를 수행하고, 다른 GPU가 작업을 수행하기 시작하고 완료가 시작될 때만 GPU0이 묶음의 역순으로 3, 2, 1 및 0 (B0,3, B0,2, B0,1, B0,0) 경로를 수행합니다.
+
+개념적으로 이는 그래디언트 누적 단계 (GAS)와 동일한 개념입니다. 파이토치에서는 `chunks`를 사용하고 DeepSpeed에서는 동일한 하이퍼파라미터를 GAS로 참조합니다.
+
+묶음으로 인해 PP는 마이크로 배치 (MBS)의 개념을 도입합니다. DP는 전역 데이터 배치 크기를 미니 배치로 나눕니다. 따라서 DP 차수가 4이고 전역 배치 크기가 1024이면 256씩 4개의 미니 배치로 분할됩니다 (1024/4). 그리고 `chunks` (또는 GAS)의 수가 32이면 마이크로 배치 크기는 8이 됩니다 (256/32). 각 파이프라인 단계는 한 번에 하나의 마이크로 배치와 함께 작동합니다.
+
+DP + PP 설정의 전역 배치 크기를 계산하려면 `mbs*chunks*dp_degree` (`8*32*4=1024`)를 수행합니다.
+
+다이어그램으로 돌아가 보겠습니다.
+
+`chunks=1`로 설정하면 매우 비효율적인 naive MP가 생성되며, 매우 큰 `chunks` 값으로 설정하면 아주 작은 마이크로 배치 크기가 생성되어 효율적이지 않을 수 있습니다. 따라서 가장 효율적인 GPU 활용을 위해 어떤 값이 가장 적절한지 실험을 해야 합니다.
+
+다이어그램에서 보이는 것처럼 "dead" 시간의 버블이 존재하여 마지막 `forward` 단계가 `backward` 단계가 파이프라인을 완료하기를 기다려야 하는 상황이 발생하지만, `chunks`의 가장 적절한 값을 찾는 것의 목적은 모든 참여하는 GPU에서 동시에 고도로 활용되는 GPU 활용을 가능하게 하여 버블의 크기를 최소화하는 것입니다.
+
+해결책은 전통적인 파이프라인 API와 더 현대적인 솔루션으로 나뉩니다. 전통적인 파이프라인 API 솔루션과 현대적인 솔루션에 대해 알아보겠습니다.
+
+전통적인 파이프라인 API 솔루션:
+- 파이토치
+- FairScale
+- DeepSpeed
+- Megatron-LM
+
+현대적인 솔루션:
+- Varuna
+- Sagemaker
+
+전통적인 파이프라인 API 솔루션의 문제점:
+- 모델을 상당히 수정해야 한다는 점이 문제입니다. 파이프라인은 모듈의 정상적인 흐름을 `nn.Sequential` 시퀀스로 다시 작성해야 하므로 모델의 설계를 변경해야 할 수 있습니다.
+- 현재 파이프라인 API는 매우 제한적입니다. 파이프라인의 매우 첫 번째 단계에서 전달되는 많은 파이썬 변수가 있는 경우 이를 해결해야 합니다. 현재 파이프라인 인터페이스는 하나의 텐서 또는 텐서의 튜플을 유일한 입력 및 출력으로 요구합니다. 이러한 텐서는 마이크로 배치로 미니 배치로 묶을 것이므로 첫 번째 차원으로 배치 크기가 있어야 합니다. 가능한 개선 사항은 여기에서 논의되고 있습니다. https://github.com/pytorch/pytorch/pull/50693
+- 파이프 단계 수준에서 조건부 제어 흐름은 불가능합니다. 예를 들어, T5와 같은 인코더-디코더 모델은 조건부 인코더 단계를 처리하기 위해 특별한 해결책이 필요합니다.
+- 각 레이어를 정렬하여 하나의 모델의 출력이 다른 모델의 입력이 되도록해야 합니다.
+
+우리는 아직 Varuna와 SageMaker로 실험하지 않았지만, 해당 논문들은 위에서 언급한 문제들의 목록을 극복했고 사용자의 모델에 대한 변경 사항이 훨씬 적게 필요하다고 보고하고 있습니다.
+
+구현:
+- [파이토치](https://pytorch.org/docs/stable/pipeline.html) (파이토치-1.8에서 초기 지원, 1.9에서 점진적으로 개선되고 1.10에서 더 개선됨). [예제](https://github.com/pytorch/pytorch/blob/master/benchmarks/distributed/pipeline/pipe.py)도 참고하세요.
+- [FairScale](https://fairscale.readthedocs.io/en/latest/tutorials/pipe.html)
+- [DeepSpeed](https://www.deepspeed.ai/tutorials/pipeline/)
+- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)은 내부 구현을 가지고 있습니다 - API 없음.
+- [Varuna](https://github.com/microsoft/varuna)
+- [SageMaker](https://arxiv.org/abs/2111.05972) - 이는 AWS에서만 사용할 수 있는 소유 솔루션입니다.
+- [OSLO](https://github.com/tunib-ai/oslo) - 이는 Hugging Face Transformers를 기반으로 구현된 파이프라인 병렬화입니다.
+
+🤗 Transformers 상태: 이 작성 시점에서 모델 중 어느 것도 완전한 PP를 지원하지 않습니다. GPT2와 T5 모델은 naive MP를 지원합니다. 주요 장애물은 모델을 `nn.Sequential`로 변환하고 모든 입력을 텐서로 가져와야 하는 것을 처리할 수 없기 때문입니다. 현재 모델에는 이러한 변환을 매우 복잡하게 만드는 많은 기능이 포함되어 있어 제거해야 합니다.
+
+기타 접근 방법:
+
+DeepSpeed, Varuna 및 SageMaker는 [교차 파이프라인(Interleaved Pipeline)](https://docs.aws.amazon.com/sagemaker/latest/dg/model-parallel-core-features.html) 개념을 사용합니다.
+
+
+여기서는 버블(유휴 시간)을 역방향 패스에 우선순위를 부여하여 최소화합니다.
+
+Varuna는 가장 효율적인 스케줄링을 찾기 위해 시뮬레이션을 사용하여 스케줄을 개선하려고 합니다.
+
+OSLO는 `nn.Sequential`로 변환하지 않고 Transformers를 기반으로 한 파이프라인 병렬화를 구현했습니다.
+
+## 텐서 병렬 처리 [[tensor-parallelism]]
+
+텐서 병렬 처리에서는 각 GPU가 텐서의 일부분만 처리하고 전체 텐서가 필요한 연산에 대해서만 전체 텐서를 집계합니다.
+
+이 섹션에서는 [Megatron-LM](https://github.com/NVIDIA/Megatron-LM) 논문인 [Efficient Large-Scale Language Model Training on GPU Clusters](https://arxiv.org/abs/2104.04473)에서의 개념과 다이어그램을 사용합니다.
+
+Transformer의 주요 구성 요소는 fully connected `nn.Linear`와 비선형 활성화 함수인 `GeLU`입니다.
+
+Megatron 논문의 표기법을 따라 행렬의 점곱 부분을 `Y = GeLU(XA)`로 표현할 수 있습니다. 여기서 `X`와 `Y`는 입력 및 출력 벡터이고 `A`는 가중치 행렬입니다.
+
+행렬 형태로 계산을 살펴보면, 행렬 곱셈을 다중 GPU로 분할할 수 있는 방법을 쉽게 알 수 있습니다:
+
+
+가중치 행렬 `A`를 `N`개의 GPU에 대해 열별로 분할하고 병렬로 행렬 곱셈 `XA_1`에서 `XA_n`까지 수행하면 `N`개의 출력 벡터 `Y_1, Y_2, ..., Y_n`가 생성되며 독립적으로 `GeLU`에 전달될 수 있습니다:
+
+
+이 원리를 사용하여 동기화가 필요하지 않은 GPU 간의 임의 깊이의 MLP를 업데이트할 수 있습니다. 그러나 결과 벡터를 샤드로부터 재구성해야 하는 마지막 단계까지는 GPU 간의 동기화가 필요합니다. Megatron-LM 논문의 저자들은 이에 대한 유용한 그림을 제공합니다:
+
+
+다중 헤드 어텐션 레이어의 병렬화는 더욱 간단합니다. 이미 독립적인 다중 헤드를 가지고 있기 때문에 이미 병렬화되어 있습니다!
+
+
+특별 고려사항: TP는 매우 빠른 네트워크가 필요하므로 한 개 이상의 노드에서 TP를 수행하는 것은 권장되지 않습니다. 실제로 노드에 4개의 GPU가 있는 경우 TP의 최대 차수는 4입니다. TP 차수가 8인 경우 최소한 8개의 GPU가 있는 노드를 사용해야 합니다.
+
+이 섹션은 원래의 [더 자세한 TP 개요](https://github.com/huggingface/transformers/issues/10321#issuecomment-783543530)를 기반으로 합니다.
+작성자는 [@anton-l](https://github.com/anton-l)입니다.
+
+SageMaker는 더 효율적인 처리를 위해 TP와 DP를 결합합니다.
+
+대체 이름:
+- DeepSpeed는 이를 [텐서 슬라이싱](https://www.deepspeed.ai/training/#model-parallelism)이라고 부릅니다.
+
+구현:
+- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)은 내부 구현을 가지고 있으므로 모델에 매우 특화되어 있습니다.
+- [parallelformers](https://github.com/tunib-ai/parallelformers) (현재는 추론에만 해당)
+- [SageMaker](https://arxiv.org/abs/2111.05972) - 이는 AWS에서만 사용할 수 있는 소유 솔루션입니다.
+- [OSLO](https://github.com/tunib-ai/oslo)은 Transformers를 기반으로 한 텐서 병렬 처리 구현을 가지고 있습니다.
+
+🤗 Transformers 현황:
+- core: 아직 핵심 부분에 구현되지 않음
+- 그러나 추론을 하려면 [parallelformers](https://github.com/tunib-ai/parallelformers)가 대부분의 모델을 지원합니다. 따라서 핵심 부분에 구현되기 전까지 그들의 것을 사용할 수 있습니다. 그리고 훈련 모드도 지원될 예정입니다.
+- Deepspeed-Inference는 CUDA 커널을 기반으로 하는 매우 빠른 추론 모드에서 BERT, GPT-2 및 GPT-Neo 모델을 지원합니다. 자세한 내용은 [여기](https://www.deepspeed.ai/tutorials/inference-tutorial/)를 참조하세요.
+
+## DP+PP [[dppp]]
+
+DeepSpeed [pipeline tutorial](https://www.deepspeed.ai/tutorials/pipeline/)에서 다음 다이어그램은 DP와 PP를 결합하는 방법을 보여줍니다.
+
+
+
+여기서 DP 랭크 0은 GPU2를 보지 못하고, DP 랭크 1은 GPU3을 보지 못하는 것이 중요합니다. DP에게는 딱 2개의 GPU인 것처럼 데이터를 공급합니다. GPU0은 PP를 사용하여 GPU2에게 일부 작업을 "비밀리에" 할당합니다. 그리고 GPU1도 GPU3을 도움으로 삼아 같은 방식으로 작업합니다.
+
+각 차원마다 적어도 2개의 GPU가 필요하므로 최소한 4개의 GPU가 필요합니다.
+
+구현:
+- [DeepSpeed](https://github.com/deepspeedai/DeepSpeed)
+- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)
+- [Varuna](https://github.com/microsoft/varuna)
+- [SageMaker](https://arxiv.org/abs/2111.05972)
+- [OSLO](https://github.com/tunib-ai/oslo)
+
+🤗 Transformers 현황: 아직 구현되지 않음
+
+## DP+PP+TP [[dppptp]]
+
+더 효율적인 훈련을 위해 PP와 TP 및 DP를 결합하여 3D 병렬 처리를 사용합니다. 다음 다이어그램에서 이를 확인할 수 있습니다.
+
+
+
+이 다이어그램은 [3D parallelism: Scaling to trillion-parameter models](https://www.microsoft.com/en-us/research/blog/deepspeed-extreme-scale-model-training-for-everyone/)이라는 블로그 글에서 확인할 수 있습니다.
+
+각 차원마다 적어도 2개의 GPU가 필요하므로 최소한 8개의 GPU가 필요합니다.
+
+구현:
+- [DeepSpeed](https://github.com/deepspeedai/DeepSpeed) - DeepSpeed는 더욱 효율적인 DP인 ZeRO-DP라고도 부릅니다.
+- [Megatron-LM](https://github.com/NVIDIA/Megatron-LM)
+- [Varuna](https://github.com/microsoft/varuna)
+- [SageMaker](https://arxiv.org/abs/2111.05972)
+- [OSLO](https://github.com/tunib-ai/oslo)
+
+🤗 Transformers 현황: 아직 구현되지 않음. PP와 TP가 없기 때문입니다.
+
+## ZeRO DP+PP+TP [[zero-dppptp]]
+
+DeepSpeed의 주요 기능 중 하나는 DP의 확장인 ZeRO입니다. ZeRO-DP에 대해 이미 [ZeRO Data Parallelism](#zero-data-parallelism)에서 논의되었습니다. 일반적으로 이는 PP나 TP를 필요로하지 않는 독립적인 기능입니다. 그러나 PP와 TP와 결합할 수도 있습니다.
+
+ZeRO-DP가 PP와 (선택적으로 TP와) 결합되면 일반적으로 ZeRO 단계 1(옵티마이저 분할)만 활성화됩니다.
+
+이론적으로는 ZeRO 단계 2(그라디언트 분할)를 파이프라인 병렬 처리와 함께 사용할 수도 있지만, 이는 성능에 나쁜 영향을 미칠 것입니다. 각 마이크로 배치마다 그라디언트를 샤딩하기 전에 추가적인 리듀스-스캐터 컬렉티브가 필요하며, 이는 잠재적으로 상당한 통신 오버헤드를 추가합니다. 파이프라인 병렬 처리의 특성상 작은 마이크로 배치가 사용되며, 산술 연산 강도(마이크로 배치 크기)를 균형 있게 유지하면서 파이프라인 버블(마이크로 배치 수)을 최소화하는 것에 중점을 둡니다. 따라서 해당 통신 비용은 문제가 될 것입니다.
+
+또한, PP로 인해 정상보다 적은 수의 레이어가 있으므로 메모리 절약은 크지 않을 것입니다. PP는 이미 그래디언트 크기를 ``1/PP``로 줄이기 때문에 그래디언트 샤딩의 절약 효과는 순수 DP보다는 미미합니다.
+
+ZeRO 단계 3도 같은 이유로 좋은 선택이 아닙니다 - 더 많은 노드 간 통신이 필요합니다.
+
+그리고 ZeRO가 있기 때문에 다른 이점은 ZeRO-Offload입니다. 이는 단계 1이므로 옵티마이저 상태를 CPU로 오프로드할 수 있습니다.
+
+구현:
+- [Megatron-DeepSpeed](https://github.com/microsoft/Megatron-DeepSpeed) 및 [BigScience의 Megatron-Deepspeed](https://github.com/bigscience-workshop/Megatron-DeepSpeed), 이전 저장소의 포크입니다.
+- [OSLO](https://github.com/tunib-ai/oslo)
+
+중요한 논문:
+
+- [Using DeepSpeed and Megatron to Train Megatron-Turing NLG 530B, A Large-Scale Generative Language Model](
+https://arxiv.org/abs/2201.11990)
+
+🤗 Transformers 현황: 아직 구현되지 않음, PP와 TP가 없기 때문입니다.
+
+## FlexFlow [[flexflow]]
+
+[FlexFlow](https://github.com/flexflow/FlexFlow)는 약간 다른 방식으로 병렬화 문제를 해결합니다.
+
+논문: ["Beyond Data and Model Parallelism for Deep Neural Networks" by Zhihao Jia, Matei Zaharia, Alex Aiken](https://arxiv.org/abs/1807.05358)
+
+이는 Sample-Operator-Attribute-Parameter를 기반으로 하는 일종의 4D 병렬화를 수행합니다.
+
+1. Sample = 데이터 병렬화 (샘플별 병렬)
+2. Operator = 단일 연산을 여러 하위 연산으로 병렬화
+3. Attribute = 데이터 병렬화 (길이별 병렬)
+4. Parameter = 모델 병렬화 (수평 또는 수직과 관계없이)
+
+예시:
+* Sample
+
+512 길이의 10개의 배치를 가정해 봅시다. 이를 sample 차원으로 2개의 장치에 병렬화하면, 10 x 512는 5 x 2 x 512가 됩니다.
+
+* Operator
+
+레이어 정규화를 수행한다면, 우선 std를 계산하고 두 번째로 mean을 계산한 다음 데이터를 정규화할 수 있습니다. Operator 병렬화는 std와 mean을 병렬로 계산할 수 있도록 합니다. 따라서 operator 차원으로 2개의 장치 (cuda:0, cuda:1)에 병렬화하면, 먼저 입력 데이터를 두 장치로 복사한 다음 cuda:0에서 std를 계산하고 cuda:1에서 동시에 mean을 계산합니다.
+
+* Attribute
+
+512 길이의 10개의 배치가 있습니다. 이를 attribute 차원으로 2개의 장치에 병렬화하면, 10 x 512는 10 x 2 x 256이 됩니다.
+
+* Parameter
+
+이는 tensor 모델 병렬화 또는 naive layer-wise 모델 병렬화와 유사합니다.
+
+
+
+이 프레임워크의 중요한 점은 (1) GPU/TPU/CPU 대 (2) RAM/DRAM 대 (3) 빠른 인트라-커넥트 대 느린 인터-커넥트와 같은 리소스를 고려하여 어디에서 어떤 병렬화를 사용할지를 알고리즘적으로 자동으로 최적화한다는 것입니다.
+
+하나 매우 중요한 측면은 FlexFlow가 정적이고 고정된 워크로드를 가진 모델에 대한 DNN 병렬화를 최적화하기 위해 설계되었다는 것입니다. 동적인 동작을 가진 모델은 반복마다 다른 병렬화 전략을 선호할 수 있습니다.
+
+따라서 이 프레임워크의 장점은 선택한 클러스터에서 30분 동안 시뮬레이션을 실행하고 이 특정 환경을 최적으로 활용하기 위한 최상의 전략을 제안한다는 것입니다. 부품을 추가/제거/교체하면 실행하고 그에 대한 계획을 다시 최적화한 후 훈련할 수 있습니다. 다른 설정은 자체적인 사용자 정의 최적화를 가질 수 있습니다.
+
+🤗 Transformers 현황: 아직 통합되지 않음. 이미 [transformers.utils.fx](https://github.com/huggingface/transformers/blob/master/src/transformers/utils/fx.py)를 통해 모델을 FX-추적할 수 있으며, 이는 FlexFlow의 선행 조건입니다. 따라서 어떤 작업을 수행해야 FlexFlow가 우리의 모델과 함께 작동할 수 있는지 파악해야 합니다.
+
+
+## 어떤 전략을 사용해야 할까요? [[which-strategy-to-use-when]]
+
+다음은 어떤 병렬화 전략을 언제 사용해야 하는지에 대한 매우 대략적인 개요입니다. 각 목록의 첫 번째 전략이 일반적으로 더 빠릅니다.
+
+**⇨ 단일 GPU**
+
+* 모델이 단일 GPU에 맞는 경우:
+
+ 1. 일반적인 사용
+
+* 모델이 단일 GPU에 맞지 않는 경우:
+
+ 1. ZeRO + CPU 및 옵션으로 NVMe 언로드
+ 2. 위와 동일하게 사용하되, 가장 큰 레이어가 단일 GPU에 맞지 않는 경우 Memory Centric Tiling(자세한 내용은 아래 참조)을 추가적으로 사용
+
+* 가장 큰 레이어가 단일 GPU에 맞지 않는 경우:
+
+1. ZeRO - [Memory Centric Tiling](https://deepspeed.readthedocs.io/en/latest/zero3.html#memory-centric-tiling) (MCT) 활성화. 이를 통해 크기가 매우 큰 레이어를 임의로 분할하여 순차적으로 실행할 수 있습니다. MCT는 GPU에 활성화된 매개변수의 수를 줄이지만 활성화 메모리에는 영향을 주지 않습니다. 현재 작성 기준으로 이 요구사항은 매우 드물기 때문에 사용자가 `torch.nn.Linear`를 수동으로 수정해야 합니다.
+
+**⇨ 단일 노드 / 다중 GPU**
+
+* 모델이 단일 GPU에 맞는 경우:
+
+ 1. DDP - 분산 DP
+ 2. ZeRO - 상황과 구성에 따라 빠를 수도 있고 그렇지 않을 수도 있습니다.
+
+* 모델이 단일 GPU에 맞지 않는 경우:
+
+ 1. PP
+ 2. ZeRO
+ 3. TP
+
+ NVLINK 또는 NVSwitch를 통한 매우 빠른 인트라-노드 연결이 있는 경우 이 세 가지 방법은 거의 동등할 것이며, 이러한 연결이 없는 경우 PP가 TP나 ZeRO보다 빠를 것입니다. 또한 TP의 차수도 영향을 줄 수 있습니다. 특정 설정에서 우승자를 찾기 위해 실험하는 것이 가장 좋습니다.
+
+ TP는 거의 항상 단일 노드 내에서 사용됩니다. 즉, TP 크기 <= 노드당 GPU 수입니다.
+
+* 가장 큰 레이어가 단일 GPU에 맞지 않는 경우:
+
+ 1. ZeRO를 사용하지 않을 경우 - PP만 사용할 수 없으므로 TP를 사용해야 합니다.
+ 2. ZeRO를 사용할 경우, "단일 GPU"의 항목과 동일한 항목 참조
+
+
+**⇨ 다중 노드 / 다중 GPU**
+
+* 빠른 노드 간 연결이 있는 경우:
+
+ 1. ZeRO - 모델에 대한 수정이 거의 필요하지 않습니다.
+ 2. PP+TP+DP - 통신이 적지만 모델에 대한 대규모 변경이 필요합니다.
+
+* 느린 노드 간 연결 및 GPU 메모리 부족한 경우:
+
+ 1. DP+PP+TP+ZeRO-1
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_special.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_special.md
new file mode 100644
index 0000000000000000000000000000000000000000..188db542f7c01f00396e64184e376bfea13744ec
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_special.md
@@ -0,0 +1,63 @@
+
+
+# Apple 실리콘에서 Pytorch 학습 [[PyTorch training on Apple silicon]]
+
+이전에는 Mac에서 모델을 학습할 때 CPU만 사용할 수 있었습니다. 그러나 이제 PyTorch v1.12의 출시로 Apple의 실리콘 GPU를 사용하여 훨씬 더 빠른 성능으로 모델을 학습할 수 있게 되었습니다. 이는 Pytorch에서 Apple의 Metal Performance Shaders (MPS)를 백엔드로 통합하면서 가능해졌습니다. [MPS 백엔드](https://pytorch.org/docs/stable/notes/mps.html)는 Pytorch 연산을 Metal 세이더로 구현하고 이 모듈들을 mps 장치에서 실행할 수 있도록 지원합니다.
+
+
+
+일부 Pytorch 연산들은 아직 MPS에서 지원되지 않아 오류가 발생할 수 있습니다. 이를 방지하려면 환경 변수 `PYTORCH_ENABLE_MPS_FALLBACK=1` 를 설정하여 CPU 커널을 대신 사용하도록 해야 합니다(이때 `UserWarning`이 여전히 표시될 수 있습니다).
+
+
+
+다른 오류가 발생할 경우 [PyTorch](https://github.com/pytorch/pytorch/issues) 리포지토리에 이슈를 등록해주세요. 현재 [`Trainer`]는 MPS 백엔드만 통합하고 있습니다.
+
+
+
+`mps` 장치를 이용하면 다음과 같은 이점들을 얻을 수 있습니다:
+
+* 로컬에서 더 큰 네트워크나 배치 크기로 학습 가능
+* GPU의 통합 메모리 아키텍처로 인해 메모리에 직접 접근할 수 있어 데이터 로딩 지연 감소
+* 클라우드 기반 GPU나 추가 GPU가 필요 없으므로 비용 절감 가능
+
+Pytorch가 설치되어 있는지 확인하고 시작하세요. MPS 가속은 macOS 12.3 이상에서 지원됩니다.
+
+```bash
+pip install torch torchvision torchaudio
+```
+
+[`TrainingArguments`]는 `mps` 장치가 사용 가능한 경우 이를 기본적으로 사용하므로 장치를 따로 설정할 필요가 없습니다. 예를 들어, MPS 백엔드를 자동으로 활성화하여 [run_glue.py](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-classification/run_glue.py) 스크립트를 아무 수정 없이 실행할 수 있습니다.
+
+```diff
+export TASK_NAME=mrpc
+
+python examples/pytorch/text-classification/run_glue.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+- --use_mps_device \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 32 \
+ --learning_rate 2e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/ \
+ --overwrite_output_dir
+```
+
+`gloco`와 `nccl`과 같은 [분산 학습 백엔드](https://pytorch.org/docs/stable/distributed.html#backends)는 `mps` 장치에서 지원되지 않으므로, MPS 백엔드에서는 단일 GPU로만 학습이 가능합니다.
+
+Mac에서 가속된 PyTorch 학습에 대한 더 자세한 내용은 [Introducing Accelerated PyTorch Training on Mac](https://pytorch.org/blog/introducing-accelerated-pytorch-training-on-mac/) 블로그 게시물에서 확인할 수 있습니다.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_tpu_tf.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_tpu_tf.md
new file mode 100644
index 0000000000000000000000000000000000000000..28d4fdafb96ca85278c3190c7c46be29397ac2f8
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perf_train_tpu_tf.md
@@ -0,0 +1,162 @@
+
+
+# TensorFlow로 TPU에서 훈련하기[[training-on-tpu-with-tensorflow]]
+
+
+
+자세한 설명이 필요하지 않고 바로 TPU 샘플 코드를 시작하고 싶다면 [우리의 TPU 예제 노트북!](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb)을 확인하세요.
+
+
+
+### TPU가 무엇인가요?[[what-is-a-tpu]]
+
+TPU는 **텐서 처리 장치**입니다. Google에서 설계한 하드웨어로, GPU처럼 신경망 내에서 텐서 연산을 더욱 빠르게 처리하기 위해 사용됩니다. 네트워크 훈련과 추론 모두에 사용할 수 있습니다. 일반적으로 Google의 클라우드 서비스를 통해 이용할 수 있지만, Google Colab과 Kaggle Kernel을 통해 소규모 TPU를 무료로 직접 이용할 수도 있습니다.
+
+[🤗 Transformers의 모든 Tensorflow 모델은 Keras 모델](https://huggingface.co/blog/tensorflow-philosophy)이기 때문에, 이 문서에서 다루는 대부분의 메소드는 대체로 모든 Keras 모델을 위한 TPU 훈련에 적용할 수 있습니다! 하지만 Transformer와 데이터 세트의 HuggingFace 생태계(hug-o-system?)에 특화된 몇 가지 사항이 있으며, 해당 사항에 대해 설명할 때 반드시 언급하도록 하겠습니다.
+
+### 어떤 종류의 TPU가 있나요?[[what-kinds-of-tpu-are-available]]
+
+신규 사용자는 TPU의 범위와 다양한 이용 방법에 대해 매우 혼란스러워하는 경우가 많습니다. **TPU 노드**와 **TPU VM**의 차이점은 가장 먼저 이해해야 할 핵심적인 구분 사항입니다.
+
+**TPU 노드**를 사용한다면, 실제로는 원격 TPU를 간접적으로 이용하는 것입니다. 네트워크와 데이터 파이프라인을 초기화한 다음, 이를 원격 노드로 전달할 별도의 VM이 필요합니다. Google Colab에서 TPU를 사용하는 경우, **TPU 노드** 방식으로 이용하게 됩니다.
+
+TPU 노드를 사용하는 것은 이를 사용하지 않는 사용자에게 예기치 않은 현상이 발생하기도 합니다! 특히, TPU는 파이썬 코드를 실행하는 기기(machine)와 물리적으로 다른 시스템에 있기 때문에 로컬 기기에 데이터를 저장할 수 없습니다. 즉, 컴퓨터의 내부 저장소에서 가져오는 데이터 파이프라인은 절대 작동하지 않습니다! 로컬 기기에 데이터를 저장하는 대신에, 데이터 파이프라인이 원격 TPU 노드에서 실행 중일 때에도 데이터 파이프라인이 계속 이용할 수 있는 Google Cloud Storage에 데이터를 저장해야 합니다.
+
+
+
+메모리에 있는 모든 데이터를 `np.ndarray` 또는 `tf.Tensor`로 맞출 수 있다면, Google Cloud Storage에 업로드할 필요 없이, Colab 또는 TPU 노드를 사용해서 해당 데이터에 `fit()` 할 수 있습니다.
+
+
+
+
+
+**🤗특수한 Hugging Face 팁🤗:** TF 코드 예제에서 볼 수 있는 `Dataset.to_tf_dataset()` 메소드와 그 상위 래퍼(wrapper)인 `model.prepare_tf_dataset()`는 모두 TPU 노드에서 작동하지 않습니다. 그 이유는 `tf.data.Dataset`을 생성하더라도 “순수한” `tf.data` 파이프라인이 아니며 `tf.numpy_function` 또는 `Dataset.from_generator()`를 사용하여 기본 HuggingFace `Dataset`에서 데이터를 전송하기 때문입니다. 이 HuggingFace `Dataset`는 로컬 디스크에 있는 데이터로 지원되며 원격 TPU 노드가 읽을 수 없습니다.
+
+
+
+TPU를 이용하는 두 번째 방법은 **TPU VM**을 사용하는 것입니다. TPU VM을 사용할 때, GPU VM에서 훈련하는 것과 같이 TPU가 장착된 기기에 직접 연결합니다. 특히 데이터 파이프라인과 관련하여, TPU VM은 대체로 작업하기 더 쉽습니다. 위의 모든 경고는 TPU VM에는 해당되지 않습니다!
+
+이 문서는 의견이 포함된 문서이며, 저희의 의견이 여기에 있습니다: **가능하면 TPU 노드를 사용하지 마세요.** TPU 노드는 TPU VM보다 더 복잡하고 디버깅하기가 더 어렵습니다. 또한 향후에는 지원되지 않을 가능성이 높습니다. Google의 최신 TPU인 TPUv4는 TPU VM으로만 이용할 수 있으므로, TPU 노드는 점점 더 "구식" 이용 방법이 될 것으로 전망됩니다. 그러나 TPU 노드를 사용하는 Colab과 Kaggle Kernel에서만 무료 TPU 이용이 가능한 것으로 확인되어, 필요한 경우 이를 다루는 방법을 설명해 드리겠습니다! 이에 대한 자세한 설명이 담긴 코드 샘플은 [TPU 예제 노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb)에서 확인하시기 바랍니다.
+
+### 어떤 크기의 TPU를 사용할 수 있나요?[[what-sizes-of-tpu-are-available]]
+
+단일 TPU(v2-8/v3-8/v4-8)는 8개의 복제본(replicas)을 실행합니다. TPU는 수백 또는 수천 개의 복제본을 동시에 실행할 수 있는 **pod**로 존재합니다. 단일 TPU를 하나 이상 사용하지만 전체 Pod보다 적게 사용하는 경우(예를 들면, v3-32), TPU 구성을 **pod 슬라이스**라고 합니다.
+
+Colab을 통해 무료 TPU에 이용하는 경우, 기본적으로 단일 v2-8 TPU를 제공받습니다.
+
+### XLA에 대해 들어본 적이 있습니다. XLA란 무엇이고 TPU와 어떤 관련이 있나요?[[i-keep-hearing-about-this-xla-thing-whats-xla-and-how-does-it-relate-to-tpus]]
+
+XLA는 최적화 컴파일러로, TensorFlow와 JAX에서 모두 사용됩니다. JAX에서는 유일한 컴파일러이지만, TensorFlow에서는 선택 사항입니다(하지만 TPU에서는 필수입니다!). Keras 모델을 훈련할 때 이를 활성화하는 가장 쉬운 방법은 `jit_compile=True` 인수를 `model.compile()`에 전달하는 것입니다. 오류가 없고 성능이 양호하다면, TPU로 전환할 준비가 되었다는 좋은 신호입니다!
+
+TPU에서 디버깅하는 것은 대개 CPU/GPU보다 조금 더 어렵기 때문에, TPU에서 시도하기 전에 먼저 XLA로 CPU/GPU에서 코드를 실행하는 것을 권장합니다. 물론 오래 학습할 필요는 없습니다. 즉, 모델과 데이터 파이프라인이 예상대로 작동하는지 확인하기 위해 몇 단계만 거치면 됩니다.
+
+
+
+XLA로 컴파일된 코드는 대체로 더 빠릅니다. 따라서 TPU에서 실행할 계획이 없더라도, `jit_compile=True`를 추가하면 성능이 향상될 수 있습니다. 하지만 XLA 호환성에 대한 아래 주의 사항을 반드시 확인하세요!
+
+
+
+
+
+**뼈아픈 경험에서 얻은 팁:** `jit_compile=True`를 사용하면 속도를 높이고 CPU/GPU 코드가 XLA와 호환되는지 검증할 수 있는 좋은 방법이지만, 실제 TPU에서 훈련할 때 그대로 남겨두면 많은 문제를 초래할 수 있습니다. XLA 컴파일은 TPU에서 암시적으로 이뤄지므로, 실제 TPU에서 코드를 실행하기 전에 해당 줄을 제거하는 것을 잊지 마세요!
+
+
+
+### 제 XLA 모델과 호환하려면 어떻게 해야 하나요?[[how-do-i-make-my-model-xla-compatible]]
+
+대부분의 경우, 여러분의 코드는 이미 XLA와 호환될 것입니다! 그러나 표준 TensorFlow에서 작동하지만, XLA에서는 작동하지 않는 몇 가지 사항이 있습니다. 이를 아래 세 가지 핵심 규칙으로 간추렸습니다:
+
+
+
+**특수한 HuggingFace 팁🤗:** 저희는 TensorFlow 모델과 손실 함수를 XLA와 호환되도록 재작성하는 데 많은 노력을 기울였습니다. 저희의 모델과 손실 함수는 대개 기본적으로 규칙 #1과 #2를 따르므로 `transformers` 모델을 사용하는 경우, 이를 건너뛸 수 있습니다. 하지만 자체 모델과 손실 함수를 작성할 때는 이러한 규칙을 잊지 마세요!
+
+
+
+#### XLA 규칙 #1: 코드에서 “데이터 종속 조건문”을 사용할 수 없습니다[[xla-rule-1-your-code-cannot-have-datadependent-conditionals]]
+
+어떤 `if`문도 `tf.Tensor` 내부의 값에 종속될 수 없다는 것을 의미합니다. 예를 들어, 이 코드 블록은 XLA로 컴파일할 수 없습니다!
+
+```python
+if tf.reduce_sum(tensor) > 10:
+ tensor = tensor / 2.0
+```
+
+처음에는 매우 제한적으로 보일 수 있지만, 대부분의 신경망 코드에서는 이를 수행할 필요가 없습니다. `tf.cond`를 사용하거나([여기](https://www.tensorflow.org/api_docs/python/tf/cond) 문서를 참조), 다음과 같이 조건문을 제거하고 대신 지표 변수를 사용하는 영리한 수학 트릭을 찾아내어 이 제한을 우회할 수 있습니다:
+
+```python
+sum_over_10 = tf.cast(tf.reduce_sum(tensor) > 10, tf.float32)
+tensor = tensor / (1.0 + sum_over_10)
+```
+
+이 코드는 위의 코드와 정확히 동일한 효과를 구현하지만, 조건문을 제거하여 문제 없이 XLA로 컴파일되도록 합니다!
+
+#### XLA 규칙 #2: 코드에서 "데이터 종속 크기"를 가질 수 없습니다[[xla-rule-2-your-code-cannot-have-datadependent-shapes]]
+
+코드에서 모든 `tf.Tensor` 객체의 크기가 해당 값에 종속될 수 없다는 것을 의미합니다. 예를 들어, `tf.unique` 함수는 입력에서 각 고유 값의 인스턴스 하나를 포함하는 `tensor`를 반환하기 때문에 XLA로 컴파일할 수 없습니다. 이 출력의 크기는 입력 `Tensor`가 얼마나 반복적인지에 따라 분명히 달라질 것이므로, XLA는 이를 처리하지 못합니다!
+
+일반적으로, 대부분의 신경망 코드는 기본값으로 규칙 2를 따릅니다. 그러나 문제가 되는 몇 가지 대표적인 사례가 있습니다. 가장 흔한 사례 중 하나는 **레이블 마스킹**을 사용하여 손실(loss)을 계산할 때, 해당 위치를 무시하도록 나타내기 위해 레이블을 음수 값으로 설정하는 경우입니다. 레이블 마스킹을 지원하는 NumPy나 PyTorch 손실 함수를 보면 [불 인덱싱](https://numpy.org/doc/stable/user/basics.indexing.html#boolean-array-indexing)을 사용하는 다음과 같은 코드를 자주 접할 수 있습니다:
+
+```python
+label_mask = labels >= 0
+masked_outputs = outputs[label_mask]
+masked_labels = labels[label_mask]
+loss = compute_loss(masked_outputs, masked_labels)
+mean_loss = torch.mean(loss)
+```
+
+이 코드는 NumPy나 PyTorch에서는 문제 없이 작동하지만, XLA에서는 손상됩니다! 왜 그럴까요? 얼마나 많은 위치가 마스킹되는지에 따라 `masked_outputs`와 `masked_labels`의 크기가 달라져서, **데이터 종속 크기**가 되기 때문입니다. 그러나 규칙 #1과 마찬가지로, 이 코드를 다시 작성하면 데이터 종속적 모양 크기가 정확히 동일한 출력을 산출할 수 있습니다.
+
+```python
+label_mask = tf.cast(labels >= 0, tf.float32)
+loss = compute_loss(outputs, labels)
+loss = loss * label_mask # Set negative label positions to 0
+mean_loss = tf.reduce_sum(loss) / tf.reduce_sum(label_mask)
+```
+
+여기서, 모든 위치에 대한 손실을 계산하지만, 평균을 계산할 때 분자와 분모 모두에서 마스크된 위치를 0으로 처리합니다. 이는 데이터 종속 크기를 방지하고 XLA 호환성을 유지하면서 첫 번째 블록과 정확히 동일한 결과를 산출합니다. 규칙 #1에서와 동일한 트릭을 사용하여 `tf.bool`을 `tf.float32`로 변환하고 이를 지표 변수로 사용합니다. 해당 트릭은 매우 유용하며, 자체 코드를 XLA로 변환해야 할 경우 기억해 두세요!
+
+#### XLA 규칙 #3: XLA는 각기 다른 입력 크기가 나타날 때마다 모델을 다시 컴파일해야 합니다[[xla-rule-3-xla-will-need-to-recompile-your-model-for-every-different-input-shape-it-sees]]
+
+이것은 가장 큰 문제입니다. 입력 크기가 매우 가변적인 경우, XLA는 모델을 반복해서 다시 컴파일해야 하므로 성능에 큰 문제가 발생할 수 있습니다. 이 문제는 토큰화 후 입력 텍스트의 길이가 가변적인 NLP 모델에서 주로 발생합니다. 다른 모달리티에서는 정적 크기가 더 흔하며, 해당 규칙이 훨씬 덜 문제시 됩니다.
+
+규칙 #3을 어떻게 우회할 수 있을까요? 핵심은 **패딩**입니다. 모든 입력을 동일한 길이로 패딩한 다음, `attention_mask`를 사용하면 어떤 XLA 문제도 없이 가변 크기에서 가져온 것과 동일한 결과를 가져올 수 있습니다. 그러나 과도한 패딩은 심각한 속도 저하를 야기할 수도 있습니다. 모든 샘플을 전체 데이터 세트의 최대 길이로 패딩하면, 무한한 패딩 토큰으로 구성된 배치가 생성되어 많은 연산과 메모리가 낭비될 수 있습니다!
+
+이 문제에 대한 완벽한 해결책은 없습니다. 하지만, 몇 가지 트릭을 시도해볼 수 있습니다. 한 가지 유용한 트릭은 **샘플 배치를 32 또는 64 토큰과 같은 숫자의 배수까지 패딩하는 것입니다.** 이는 토큰 수가 소폭 증가하지만, 모든 입력 크기가 32 또는 64의 배수여야 하기 때문에 고유한 입력 크기의 수가 대폭 줄어듭니다. 고유한 입력 크기가 적다는 것은 XLA 컴파일 횟수가 적어진다는 것을 의미합니다!
+
+
+
+**🤗특수한 HuggingFace 팁🤗:** 토크나이저와 데이터 콜레이터에 도움이 될 수 있는 메소드가 있습니다. 토크나이저를 불러올 때 `padding="max_length"` 또는 `padding="longest"`를 사용하여 패딩된 데이터를 출력하도록 할 수 있습니다. 토크나이저와 데이터 콜레이터는 나타나는 고유한 입력 크기의 수를 줄이기 위해 사용할 수 있는 `pad_to_multiple_of` 인수도 있습니다!
+
+
+
+### 실제 TPU로 모델을 훈련하려면 어떻게 해야 하나요?[[how-do-i-actually-train-my-model-on-tpu]]
+
+훈련이 XLA와 호환되고 (TPU 노드/Colab을 사용하는 경우) 데이터 세트가 적절하게 준비되었다면, TPU에서 실행하는 것은 놀랍도록 쉽습니다! 코드에서 몇 줄만 추가하여, TPU를 초기화하고 모델과 데이터 세트가 `TPUStrategy` 범위 내에 생성되도록 변경하면 됩니다. [우리의 TPU 예제 노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb)을 참조하여 실제로 작동하는 모습을 확인해 보세요!
+
+### 요약[[summary]]
+
+여기에 많은 내용이 포함되어 있으므로, TPU 훈련을 위한 모델을 준비할 때 따를 수 있는 간략한 체크리스트로 요약해 보겠습니다:
+
+- 코드가 XLA의 세 가지 규칙을 따르는지 확인합니다.
+- CPU/GPU에서 `jit_compile=True`로 모델을 컴파일하고 XLA로 훈련할 수 있는지 확인합니다.
+- 데이터 세트를 메모리에 가져오거나 TPU 호환 데이터 세트를 가져오는 방식을 사용합니다([노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb) 참조)
+- 코드를 Colab(accelerator가 “TPU”로 설정됨) 또는 Google Cloud의 TPU VM으로 마이그레이션합니다.
+- TPU 초기화 코드를 추가합니다([노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb) 참조)
+- `TPUStrategy`를 생성하고 데이터 세트를 가져오는 것과 모델 생성이 `strategy.scope()` 내에 있는지 확인합니다([노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/tpu_training-tf.ipynb) 참조)
+- TPU로 이동할 때 `jit_compile=True`를 다시 설정하는 것을 잊지 마세요!
+- 🙏🙏🙏🥺🥺🥺
+- model.fit()을 불러옵니다.
+- 여러분이 해냈습니다!
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/performance.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/performance.md
new file mode 100644
index 0000000000000000000000000000000000000000..226bd5f249af5da28d4af4c33251f3eb2d588721
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/performance.md
@@ -0,0 +1,96 @@
+
+
+# 성능 및 확장성 [[performance-and-scalability]]
+
+점점 더 큰 규모의 트랜스포머 모델을 훈련하고 프로덕션에 배포하는 데에는 다양한 어려움이 따릅니다. 훈련 중에는 모델이 사용 가능한 GPU 메모리보다 더 많은 메모리를 필요로 하거나 훈련 속도가 매우 느릴 수 있으며, 추론을 위해 배포할 때는 제품 환경에서 요구되는 처리량으로 인해 과부하가 발생할 수 있습니다. 이 문서는 이러한 문제를 극복하고 사용 사례에 가장 적합한 설정을 찾도록 도움을 주기 위해 설계되었습니다. 훈련과 추론으로 가이드를 분할했는데, 이는 각각 다른 문제와 해결 방법이 있기 때문입니다. 그리고 각 가이드에는 다양한 종류의 하드웨어 설정에 대한 별도의 가이드가 있습니다(예: 훈련을 위한 단일 GPU vs 다중 GPU 또는 추론을 위한 CPU vs GPU).
+
+
+
+이 문서는 사용자의 상황에 유용할 수 있는 방법들에 대한 개요 및 시작점 역할을 합니다.
+
+## 훈련 [[training]]
+
+효율적인 트랜스포머 모델 훈련에는 GPU나 TPU와 같은 가속기가 필요합니다. 가장 일반적인 경우는 단일 GPU만 사용하는 경우지만, 다중 GPU 및 CPU 훈련에 대한 섹션도 있습니다(곧 더 많은 내용이 추가될 예정).
+
+
+
+ 참고: 단일 GPU 섹션에서 소개된 대부분의 전략(예: 혼합 정밀도 훈련 또는 그라디언트 누적)은 일반적인 모델 훈련에도 적용되므로, 다중 GPU나 CPU 훈련과 같은 섹션을 살펴보기 전에 꼭 참고하시길 바랍니다.
+
+
+
+### 단일 GPU [[single-gpu]]
+
+단일 GPU에서 대규모 모델을 훈련하는 것은 어려울 수 있지만, 이를 가능하게 하는 여러 가지 도구와 방법이 있습니다. 이 섹션에서는 혼합 정밀도 훈련, 그라디언트 누적 및 체크포인팅, 효율적인 옵티마이저, 최적의 배치 크기를 결정하기 위한 전략 등에 대해 논의합니다.
+
+[단일 GPU 훈련 섹션으로 이동](perf_train_gpu_one)
+
+### 다중 GPU [[multigpu]]
+
+단일 GPU에서 훈련하는 것이 너무 느리거나 대규모 모델에 적합하지 않은 경우도 있습니다. 다중 GPU 설정으로 전환하는 것은 논리적인 단계이지만, 여러 GPU에서 한 번에 훈련하려면 각 GPU마다 모델의 전체 사본을 둘지, 혹은 모델 자체도 여러 GPU에 분산하여 둘지 등 새로운 결정을 내려야 합니다. 이 섹션에서는 데이터, 텐서 및 파이프라인 병렬화에 대해 살펴봅니다.
+
+[다중 GPU 훈련 섹션으로 이동](perf_train_gpu_many)
+
+### CPU [[cpu]]
+
+
+[CPU 훈련 섹션으로 이동](perf_train_cpu)
+
+
+### TPU [[tpu]]
+
+[_곧 제공될 예정_](perf_train_tpu)
+
+### 특수한 하드웨어 [[specialized-hardware]]
+
+[_곧 제공될 예정_](perf_train_special)
+
+## 추론 [[inference]]
+
+제품 및 서비스 환경에서 대규모 모델을 효율적으로 추론하는 것은 모델을 훈련하는 것만큼 어려울 수 있습니다. 이어지는 섹션에서는 CPU 및 단일/다중 GPU 설정에서 추론을 진행하는 단계를 살펴봅니다.
+
+### CPU [[cpu]]
+
+[CPU 추론 섹션으로 이동](perf_infer_cpu)
+
+### 단일 GPU [[single-gpu]]
+
+[단일 GPU 추론 섹션으로 이동](perf_infer_gpu_one)
+
+### 다중 GPU [[multigpu]]
+
+[다중 GPU 추론 섹션으로 이동](perf_infer_gpu_many)
+
+### 특수한 하드웨어 [[specialized-hardware]]
+
+[_곧 제공될 예정_](perf_infer_special)
+
+## 하드웨어 [[hardware]]
+
+하드웨어 섹션에서는 자신만의 딥러닝 장비를 구축할 때 유용한 팁과 요령을 살펴볼 수 있습니다.
+
+[하드웨어 섹션으로 이동](perf_hardware)
+
+
+## 기여하기 [[contribute]]
+
+이 문서는 완성되지 않은 상태이며, 추가해야 할 내용이나 수정 사항이 많이 있습니다. 따라서 추가하거나 수정할 내용이 있으면 주저하지 말고 PR을 열어 주시거나, 자세한 내용을 논의하기 위해 Issue를 시작해 주시기 바랍니다.
+
+A가 B보다 좋다고 하는 기여를 할 때는, 재현 가능한 벤치마크와/또는 해당 정보의 출처 링크를 포함해주세요(당신으로부터의 직접적인 정보가 아닌 경우).
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perplexity.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perplexity.md
new file mode 100644
index 0000000000000000000000000000000000000000..9de84a5f289b942875aa88386f430cc67e306bb9
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/perplexity.md
@@ -0,0 +1,135 @@
+
+
+# 고정 길이 모델의 펄플렉서티(Perplexity)[[perplexity-of-fixedlength-models]]
+
+[[open-in-colab]]
+
+펄플렉서티(Perplexity, PPL)는 가장 일반적인 언어 모델 평가지표 중 하나입니다.
+자세히 알아보기 전에 이 평가지표는 고전적인 언어 모델(자기회귀 또는 인과적 언어 모델이라고도 함)에만 적용되며 BERT와 같은 마스킹된 언어 모델에는 잘 적용하지 않습니다 (BERT는 [summary of the models](../en/model_summary) 문서를 참고하세요).
+
+펄플렉서티는 시퀀스의 음의 로그 우도(negative log-likelihood, NLL) 값의 평균에 지수(exponentiate)를 취한 값으로 정의됩니다.
+토큰화된 시퀀스 \\(X = (x_0, x_1, \dots, x_t)\\) 가 있을 때, \\(X\\) 의 펄플렉서티는 아래 수식과 같이 구할 수 있습니다.
+
+$$\text{PPL}(X) = \exp \left\{ {-\frac{1}{t}\sum_i^t \log p_\theta (x_i|x_{
+
+그러나 모델의 근사치를 구할 때는 일반적으로 모델이 처리할 수 있는 토큰 수에 제한이 있습니다.
+예를 들어, 가장 큰 버전의 [GPT-2](model_doc/gpt2)는 토큰의 길이가 1024로 고정되어 있습니다.
+따라서 \\(t\\) 가 1024보다 큰 경우에 \\(p_\theta(x_t|x_{
+
+이 방법은 각 부분의 펄플렉서티를 한 번의 포워드 패스로 계산할 수 있어 빠르지만 일반적으로 더 높은(더 나쁜) PPL을 산출합니다.
+왜냐하면 대부분의 예측 단계에서 모델의 컨텍스트가 적기 때문입니다.
+
+대신, 고정 길이 모델의 PPL은 슬라이딩 윈도우 전략으로 평가해야 합니다.
+이 전략에는 컨텍스트 윈도우을 반복적으로 슬라이딩해 모델이 각 예측을 수행할 때 더 많은 컨텍스트를 갖도록 하는 작업이 포함됩니다.
+
+
+
+이는 시퀀스 확률의 실제 분해에 더 가까운 근사치이며 일반적으로 더 유리한 점수를 산출합니다.
+단점은 말뭉치의 각 토큰에 대해 별도의 포워드 패스가 필요하다는 것입니다.
+현실적으로 좋은 절충안은 한 번에 한 토큰씩 슬라이딩하는 것이 아니라 더 큰 간격으로 컨텍스트를 이동하는 스트라이드가 적용된 슬라이딩 윈도우을 사용하는 것입니다.
+이렇게 하면 계산을 훨씬 더 빠르게 진행하면서도 모델에 각 단계에서 예측을 수행할 수 있는 긴 컨텍스트를 제공할 수 있습니다.
+
+## 예제: 🤗 Transformers에서 GPT-2로 펄플렉서티(perplexity) 계산하기[[example-calculating-perplexity-with-gpt2-in-transformers]]
+
+이제 GPT-2로 위의 과정을 시연해 보겠습니다.
+
+```python
+from transformers import GPT2LMHeadModel, GPT2TokenizerFast
+
+device = "cuda"
+model_id = "openai-community/gpt2-large"
+model = GPT2LMHeadModel.from_pretrained(model_id).to(device)
+tokenizer = GPT2TokenizerFast.from_pretrained(model_id)
+```
+
+WikiText-2 데이터 세트를 가져오고 몇 가지 슬라이딩 윈도우 전략을 사용해 펄플렉서티를 계산해보겠습니다.
+이 데이터 세트는 크기가 작고 포워드 패스 한 번만 수행하기 때문에 전체 데이터 세트를 메모리에 가져오고 인코딩할 수 있습니다.
+
+```python
+from datasets import load_dataset
+
+test = load_dataset("wikitext", "wikitext-2-raw-v1", split="test")
+encodings = tokenizer("\n\n".join(test["text"]), return_tensors="pt")
+```
+
+🤗 Transformers를 사용하면 모델의 `labels`로 `input_ids`를 전달해 각 토큰에 대한 평균 음의 우도 값을 손실로 반환할 수 있습니다.
+하지만 슬라이딩 윈도우 방식을 사용하면 각 반복마다 모델에 전달하는 토큰이 겹칩니다.
+컨텍스트로 처리하는 토큰에 대한 로그 우도 값이 손실에 포함되는 것을 원하지 않기 때문에 이러한 토큰의 `input_ids`를 `-100`으로 설정하여 무시할 수 있습니다.
+
+다음은 스트라이드(stride)를 `512`로 사용한 예시입니다.
+즉, 모델이 한 토큰의 조건부 우도 값을 계산할 때 컨텍스트에 최소한 512개의 토큰이 포함되어있다는 의미입니다 (해당 토큰 앞에 512개의 토큰이 있는 경우).
+
+```python
+import torch
+from tqdm import tqdm
+
+max_length = model.config.n_positions
+stride = 512
+seq_len = encodings.input_ids.size(1)
+
+nlls = []
+prev_end_loc = 0
+for begin_loc in tqdm(range(0, seq_len, stride)):
+ end_loc = min(begin_loc + max_length, seq_len)
+ trg_len = end_loc - prev_end_loc # 마지막 루프의 스트라이드 값과 다를 수 있음
+ input_ids = encodings.input_ids[:, begin_loc:end_loc].to(device)
+ target_ids = input_ids.clone()
+ target_ids[:, :-trg_len] = -100
+
+ with torch.no_grad():
+ outputs = model(input_ids, labels=target_ids)
+
+ # 손실은 모든 유효한 레이블에 대한 평균값을 구하는 교차 엔트로피(cross entropy)로 계산됩니다.
+ # 나이브 베이지안 모델은 내부적으로 레이블을 왼쪽으로 1개씩 밀기 때문에, (타켓 - 1)개 만큼의 레이블에 대해 손실을 계산합니다.
+ neg_log_likelihood = outputs.loss
+
+ nlls.append(neg_log_likelihood)
+
+ prev_end_loc = end_loc
+ if end_loc == seq_len:
+ break
+
+ppl = torch.exp(torch.stack(nlls).mean())
+```
+
+스트라이드를 최대 입력 길이와 동일하게 설정하면 위에서 설명한 차선책인 비슬라이딩 윈도우 전략과 동일합니다.
+일반적으로 스트라이드가 작을수록 모델이 각 예측을 할 때 더 많은 컨텍스트를 볼 수 있게 되어 펄플렉서티 값이 좋아집니다.
+
+위의 계산을 토큰이 겹치지 않도록 `stride = 1024`로 설정하면 PPL은 `19.44`로 GPT-2 논문에서 보고된 `19.93`과 거의 동일합니다.
+`stride = 512`로 슬라이딩 윈도우 전략을 사용하면 PPL은 `16.45`로 떨어집니다.
+이는 더 좋은 점수일 뿐만 아니라 시퀀스 확률의 실제 자동 회귀 분해에 더 가까운 방식으로 계산됩니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/philosophy.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/philosophy.md
new file mode 100644
index 0000000000000000000000000000000000000000..e303709a11b8336a3cae1f6a6c5321ef953c4bc9
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/philosophy.md
@@ -0,0 +1,66 @@
+
+
+# 이념과 목표 [[philosophy]]
+
+🤗 Transformers는 다음과 같은 목적으로 만들어진 독자적인 라이브러리입니다:
+
+- 대규모 Transformers 모델을 사용하거나 연구하거나 확장하려는 기계 학습 연구원 및 교육자를 위한 것입니다.
+- 모델을 미세 조정하거나 제작용으로 사용하고자 하는 실전 개발자를 위한 것입니다.
+- 특정 기계 학습 작업을 해결하기 위해 사전훈련된 모델을 다운로드하고 사용하기만 하려는 엔지니어를 위한 것입니다.
+
+이 라이브러리는 두 가지 주요 목표를 가지고 설계되었습니다:
+
+1. 사용하기 쉽고 빠르게 만드는 것:
+
+- 학습해야 할 사용자 대상 추상화의 수를 제한했습니다. 실제로 거의 추상화가 없으며, 각 모델을 사용하기 위해 필요한 세 가지 표준 클래스인 [configuration](main_classes/configuration), [models](main_classes/model) 및 전처리 클래스인 ([tokenizer](main_classes/tokenizer)는 NLP용, [image processor](main_classes/image_processor)는 비전용, [feature extractor](main_classes/feature_extractor)는 오디오용, [processor](main_classes/processors)는 멀티모달 입력용)만 사용합니다.
+- 이러한 클래스는 공통적인 `from_pretrained()` 메서드를 사용하여 미리 훈련된 인스턴스에서 간단하고 통일된 방식으로 초기화할 수 있습니다. 이 메소드는 미리 훈련된 체크포인트에서 관련 클래스 인스턴스와 관련 데이터(구성의 하이퍼파라미터, 토크나이저의 어휘, 모델의 가중치)를 (필요한 경우) 다운로드하고 캐시하며 가져옵니다. 체크포인트는 [Hugging Face Hub](https://huggingface.co/models)에서 제공되거나 사용자 자체의 저장된 체크포인트에서 제공됩니다.
+- 이 세 가지 기본 클래스 위에 라이브러리는 [`pipeline`] API를 제공하여 주어진 작업에 대해 모델을 빠르게 추론하는 데 사용하고, [`Trainer`]를 제공하여 PyTorch 모델을 빠르게 훈련하거나 미세 조정할 수 있도록 합니다(모든 TensorFlow 모델은 `Keras.fit`과 호환됩니다).
+- 결과적으로, 이 라이브러리는 신경망을 구축하기 위한 모듈식 도구 상자가 아닙니다. 라이브러리를 확장하거나 구축하려면 일반적인 Python, PyTorch, TensorFlow, Keras 모듈을 사용하고 라이브러리의 기본 클래스를 상속하여 모델 로딩 및 저장과 같은 기능을 재사용하면 됩니다. 모델에 대한 코딩 철학에 대해 더 자세히 알고 싶다면 [Repeat Yourself](https://huggingface.co/blog/transformers-design-philosophy) 블로그 글을 확인해보세요.
+
+2. 원래 모델과 가능한 한 근접한 성능을 제공하는 최신 모델을 제공하는 것:
+
+- 각 아키텍처에 대해 공식 저자가 제공한 결과를 재현하는 적어도 한 가지 예제를 제공합니다.
+- 코드는 원래 코드와 가능한 한 유사하게 유지되므로 PyTorch 코드는 TensorFlow 코드로 변환되어 *pytorchic*하지 않을 수 있고, 그 반대의 경우도 마찬가지입니다.
+
+기타 목표 몇 가지:
+
+- 모델의 내부를 가능한 일관되게 노출시키기:
+
+ - 전체 은닉 상태와 어텐션 가중치에 대한 액세스를 단일 API를 사용하여 제공합니다.
+ - 전처리 클래스 및 기본 모델 API는 모델 간에 쉽게 전환할 수 있도록 표준화되어 있습니다.
+
+- 미세 조정 및 모델 탐색을 위한 유망한 도구들을 주관적으로 선택하기:
+
+ - 미세 조정을 위해 어휘 및 임베딩에 새로운 토큰을 간단하고 일관된 방식으로 추가하는 방법을 제공합니다.
+ - Transformer 헤드를 마스킹하고 가지치기하는 간단한 방법을 제공합니다.
+
+- PyTorch, TensorFlow 2.0 및 Flax 간에 쉽게 전환할 수 있도록 하여 하나의 프레임워크로 훈련하고 다른 프레임워크로 추론할 수 있게 합니다.
+
+## 주요 개념 [[main-concepts]]
+
+이 라이브러리는 각 모델에 대해 세 가지 유형의 클래스를 기반으로 구축되었습니다:
+
+- **모델 클래스**는 라이브러리에서 제공하는 사전 훈련된 가중치와 함께 작동하는 PyTorch 모델([torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module)), Keras 모델([tf.keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model)), JAX/Flax 모델([flax.linen.Module](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html))일 수 있습니다.
+- **구성 클래스**는 모델을 구축하는 데 필요한 하이퍼파라미터(예: 레이어 수 및 은닉 크기)를 저장합니다. 구성 클래스를 직접 인스턴스화할 필요는 없습니다. 특히, 수정 없이 고 사전 학습된 모델을 사용하는 경우 모델을 생성하면 모델의 일부인 구성을 자동으로 인스턴스화됩니다.
+- **전처리 클래스**는 원시 데이터를 모델이 수용하는 형식으로 변환합니다. [Tokenizer](main_classes/tokenizer)는 각 모델의 어휘를 저장하고, 문자열을 토큰 임베딩 인덱스 리스트로 인코딩하고 디코딩하기 위한 메소드를 제공합니다. [Image processors](main_classes/image_processor)는 비전 입력을 전처리하고, [feature extractors](main_classes/feature_extractor)는 오디오 입력을 전처리하며, [processor](main_classes/processors)는 멀티모달 입력을 처리합니다.
+
+모든 이러한 클래스는 사전 훈련된 인스턴스에서 인스턴스화하고 로컬로 저장하며, 세 가지 메소드를 사용하여 Hub에서 공유할 수 있습니다:
+
+- `from_pretrained()` 메소드를 사용하면 라이브러리 자체에서 제공하는 사전 훈련된 버전(지원되는 모델은 [Model Hub](https://huggingface.co/models)에서 찾을 수 있음)이나 사용자가 로컬로 저장한 경우(또는 서버에 저장한 경우)의 모델, 구성 및 전처리 클래스를 인스턴스화할 수 있습니다.
+- `save_pretrained()` 메소드를 사용하면 모델, 구성 및 전처리 클래스를 로컬로 저장하여 `from_pretrained()`를 사용하여 다시 가져올 수 있습니다.
+- `push_to_hub()` 메소드를 사용하면 모델, 구성 및 전처리 클래스를 Hub에 공유하여 모두에게 쉽게 접근할 수 있습니다.
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/pipeline_tutorial.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/pipeline_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..2f166fc6939f3206f3b03490c140a5c3f360045f
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/pipeline_tutorial.md
@@ -0,0 +1,243 @@
+
+
+# 추론을 위한 Pipeline[[pipelines-for-inference]]
+
+[`pipeline`]을 사용하면 언어, 컴퓨터 비전, 오디오 및 멀티모달 태스크에 대한 추론을 위해 [Hub](https://huggingface.co/models)의 어떤 모델이든 쉽게 사용할 수 있습니다. 특정 분야에 대한 경험이 없거나, 모델을 이루는 코드가 익숙하지 않은 경우에도 [`pipeline`]을 사용해서 추론할 수 있어요! 이 튜토리얼에서는 다음을 배워보겠습니다.
+
+* 추론을 위해 [`pipeline`]을 사용하는 방법
+* 특정 토크나이저 또는 모델을 사용하는 방법
+* 언어, 컴퓨터 비전, 오디오 및 멀티모달 태스크에서 [`pipeline`]을 사용하는 방법
+
+
+
+지원하는 모든 태스크와 쓸 수 있는 매개변수를 담은 목록은 [`pipeline`] 설명서를 참고해주세요.
+
+
+
+## Pipeline 사용하기[[pipeline-usage]]
+
+각 태스크마다 고유의 [`pipeline`]이 있지만, 개별 파이프라인을 담고있는 추상화된 [`pipeline`]를 사용하는 것이 일반적으로 더 간단합니다. [`pipeline`]은 태스크에 알맞게 추론이 가능한 기본 모델과 전처리 클래스를 자동으로 로드합니다.
+
+1. 먼저 [`pipeline`]을 생성하고 태스크를 지정하세요.
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline(task="automatic-speech-recognition")
+```
+
+2. 그리고 [`pipeline`]에 입력을 넣어주세요.
+
+```py
+>>> generator("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': 'I HAVE A DREAM BUT ONE DAY THIS NATION WILL RISE UP LIVE UP THE TRUE MEANING OF ITS TREES'}
+```
+
+기대했던 결과가 아닌가요? Hub에서 [가장 많이 다운로드된 자동 음성 인식 모델](https://huggingface.co/models?pipeline_tag=automatic-speech-recognition&sort=downloads)로 더 나은 결과를 얻을 수 있는지 확인해보세요.
+다음은 [openai/whisper-large](https://huggingface.co/openai/whisper-large)로 시도해보겠습니다.
+
+```py
+>>> generator = pipeline(model="openai/whisper-large")
+>>> generator("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+훨씬 더 나아졌군요!
+Hub의 모델들은 여러 다양한 언어와 전문분야를 아우르기 때문에 꼭 자신의 언어나 분야에 특화된 모델을 찾아보시기 바랍니다.
+브라우저를 벗어날 필요없이 Hub에서 직접 모델의 출력을 확인하고 다른 모델과 비교해서 자신의 상황에 더 적합한지, 애매한 입력을 더 잘 처리하는지도 확인할 수 있습니다.
+만약 상황에 알맞는 모델을 없다면 언제나 직접 [훈련](training)시킬 수 있습니다!
+
+입력이 여러 개 있는 경우, 리스트 형태로 전달할 수 있습니다.
+
+```py
+generator(
+ [
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac",
+ "https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/1.flac",
+ ]
+)
+```
+
+전체 데이터세트을 순회하거나 웹서버에 올려두어 추론에 사용하고 싶다면, 각 상세 페이지를 참조하세요.
+
+[데이터세트에서 Pipeline 사용하기](#using-pipelines-on-a-dataset)
+
+[웹서버에서 Pipeline 사용하기](./pipeline_webserver)
+
+## 매개변수[[parameters]]
+
+[`pipeline`]은 많은 매개변수를 지원합니다. 특정 태스크용인 것도 있고, 범용인 것도 있습니다.
+일반적으로 원하는 위치에 어디든 매개변수를 넣을 수 있습니다.
+
+```py
+generator(model="openai/whisper-large", my_parameter=1)
+out = generate(...) # This will use `my_parameter=1`.
+out = generate(..., my_parameter=2) # This will override and use `my_parameter=2`.
+out = generate(...) # This will go back to using `my_parameter=1`.
+```
+
+중요한 3가지 매개변수를 살펴보겠습니다.
+
+### 기기(device)[[device]]
+
+`device=n`처럼 기기를 지정하면 파이프라인이 자동으로 해당 기기에 모델을 배치합니다.
+파이토치에서나 텐서플로우에서도 모두 작동합니다.
+
+```py
+generator(model="openai/whisper-large", device=0)
+```
+
+모델이 GPU 하나에 돌아가기 버겁다면, `device_map="auto"`를 지정해서 🤗 [Accelerate](https://huggingface.co/docs/accelerate)가 모델 가중치를 어떻게 로드하고 저장할지 자동으로 결정하도록 할 수 있습니다.
+
+```py
+#!pip install accelerate
+generator(model="openai/whisper-large", device_map="auto")
+```
+
+### 배치 사이즈[[batch-size]]
+
+기본적으로 파이프라인은 [여기](https://huggingface.co/docs/transformers/main_classes/pipelines#pipeline-batching)에 나온 이유로 추론을 일괄 처리하지 않습니다. 간단히 설명하자면 일괄 처리가 반드시 더 빠르지 않고 오히려 더 느려질 수도 있기 때문입니다.
+
+하지만 자신의 상황에 적합하다면, 이렇게 사용하세요.
+
+```py
+generator(model="openai/whisper-large", device=0, batch_size=2)
+audio_filenames = [f"audio_{i}.flac" for i in range(10)]
+texts = generator(audio_filenames)
+```
+
+파이프라인 위 제공된 10개의 오디오 파일을 추가로 처리하는 코드 없이 (일괄 처리에 보다 효과적인 GPU 위) 모델에 2개씩 전달합니다.
+출력은 일괄 처리하지 않았을 때와 똑같아야 합니다. 파이프라인에서 속도를 더 낼 수도 있는 방법 중 하나일 뿐입니다.
+
+파이프라인은 일괄 처리의 복잡한 부분을 줄여주기도 합니다. (예를 들어 긴 오디오 파일처럼) 여러 부분으로 나눠야 모델이 처리할 수 있는 것을 [*chunk batching*](./main_classes/pipelines#pipeline-chunk-batching)이라고 하는데, 파이프라인을 사용하면 자동으로 나눠줍니다.
+
+### 특정 태스크용 매개변수[[task-specific-parameters]]
+
+각 태스크마다 구현할 때 유연성과 옵션을 제공하기 위해 태스크용 매개변수가 있습니다.
+예를 들어 [`transformers.AutomaticSpeechRecognitionPipeline.__call__`] 메서드에는 동영상의 자막을 넣을 때 유용할 것 같은 `return_timestamps` 매개변수가 있습니다.
+
+```py
+>>> # Not using whisper, as it cannot provide timestamps.
+>>> generator = pipeline(model="facebook/wav2vec2-large-960h-lv60-self", return_timestamps="word")
+>>> generator("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': 'I HAVE A DREAM BUT ONE DAY THIS NATION WILL RISE UP AND LIVE OUT THE TRUE MEANING OF ITS CREED', 'chunks': [{'text': 'I', 'timestamp': (1.22, 1.24)}, {'text': 'HAVE', 'timestamp': (1.42, 1.58)}, {'text': 'A', 'timestamp': (1.66, 1.68)}, {'text': 'DREAM', 'timestamp': (1.76, 2.14)}, {'text': 'BUT', 'timestamp': (3.68, 3.8)}, {'text': 'ONE', 'timestamp': (3.94, 4.06)}, {'text': 'DAY', 'timestamp': (4.16, 4.3)}, {'text': 'THIS', 'timestamp': (6.36, 6.54)}, {'text': 'NATION', 'timestamp': (6.68, 7.1)}, {'text': 'WILL', 'timestamp': (7.32, 7.56)}, {'text': 'RISE', 'timestamp': (7.8, 8.26)}, {'text': 'UP', 'timestamp': (8.38, 8.48)}, {'text': 'AND', 'timestamp': (10.08, 10.18)}, {'text': 'LIVE', 'timestamp': (10.26, 10.48)}, {'text': 'OUT', 'timestamp': (10.58, 10.7)}, {'text': 'THE', 'timestamp': (10.82, 10.9)}, {'text': 'TRUE', 'timestamp': (10.98, 11.18)}, {'text': 'MEANING', 'timestamp': (11.26, 11.58)}, {'text': 'OF', 'timestamp': (11.66, 11.7)}, {'text': 'ITS', 'timestamp': (11.76, 11.88)}, {'text': 'CREED', 'timestamp': (12.0, 12.38)}]}
+```
+
+보시다시피 모델이 텍스트를 추론할 뿐만 아니라 각 단어를 말한 시점까지도 출력했습니다.
+
+태스크마다 다양한 매개변수를 가지고 있는데요. 원하는 태스크의 API를 참조해서 바꿔볼 수 있는 여러 매개변수를 살펴보세요!
+지금까지 다뤄본 [`~transformers.AutomaticSpeechRecognitionPipeline`]에는 `chunk_length_s` 매개변수가 있습니다. 영화나 1시간 분량의 동영상의 자막 작업을 할 때처럼, 일반적으로 모델이 자체적으로 처리할 수 없는 매우 긴 오디오 파일을 처리할 때 유용하죠.
+
+
+도움이 될 만한 매개변수를 찾지 못했다면 언제든지 [요청](https://github.com/huggingface/transformers/issues/new?assignees=&labels=feature&template=feature-request.yml)해주세요!
+
+
+## 데이터세트에서 Pipeline 사용하기[[using-pipelines-on-a-dataset]]
+
+파이프라인은 대규모 데이터세트에서도 추론 작업을 할 수 있습니다. 이때 이터레이터를 사용하는 걸 추천드립니다.
+
+```py
+def data():
+ for i in range(1000):
+ yield f"My example {i}"
+
+
+pipe = pipe(model="openai-community/gpt2", device=0)
+generated_characters = 0
+for out in pipe(data()):
+ generated_characters += len(out["generated_text"])
+```
+
+이터레이터 `data()`는 각 결과를 호출마다 생성하고, 파이프라인은 입력이 순회할 수 있는 자료구조임을 자동으로 인식하여 GPU에서 기존 데이터가 처리되는 동안 새로운 데이터를 가져오기 시작합니다.(이때 내부적으로 [DataLoader](https://pytorch.org/docs/stable/data.html#torch.utils.data.DataLoader)를 사용해요.) 이 과정은 전체 데이터세트를 메모리에 적재하지 않고도 GPU에 최대한 빠르게 새로운 작업을 공급할 수 있기 때문에 중요합니다.
+
+그리고 일괄 처리가 더 빠를 수 있기 때문에, `batch_size` 매개변수를 조정해봐도 좋아요.
+
+데이터세트를 순회하는 가장 간단한 방법은 🤗 [Datasets](https://github.com/huggingface/datasets/)를 활용하는 것인데요.
+
+```py
+# KeyDataset is a util that will just output the item we're interested in.
+from transformers.pipelines.pt_utils import KeyDataset
+
+pipe = pipeline(model="hf-internal-testing/tiny-random-wav2vec2", device=0)
+dataset = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation[:10]")
+
+for out in pipe(KeyDataset(dataset["audio"])):
+ print(out)
+```
+
+
+## 웹서버에서 Pipeline 사용하기[[using-pipelines-for-a-webserver]]
+
+
+추론 엔진을 만드는 과정은 따로 페이지를 작성할만한 복잡한 주제입니다.
+
+
+[Link](./pipeline_webserver)
+
+## 비전 Pipeline[[vision-pipeline]]
+
+비전 태스크를 위해 [`pipeline`]을 사용하는 일은 거의 동일합니다.
+
+태스크를 지정하고 이미지를 분류기에 전달하면 됩니다. 이미지는 인터넷 링크 또는 로컬 경로의 형태로 전달해주세요. 예를 들어 아래에 표시된 고양이는 어떤 종인가요?
+
+
+
+```py
+>>> from transformers import pipeline
+
+>>> vision_classifier = pipeline(model="google/vit-base-patch16-224")
+>>> preds = vision_classifier(
+... images="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4335, 'label': 'lynx, catamount'}, {'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}, {'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}, {'score': 0.0239, 'label': 'Egyptian cat'}, {'score': 0.0229, 'label': 'tiger cat'}]
+```
+
+### 텍스트 Pipeline[[text-pipeline]]
+
+NLP 태스크를 위해 [`pipeline`]을 사용하는 일도 거의 동일합니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> # This model is a `zero-shot-classification` model.
+>>> # It will classify text, except you are free to choose any label you might imagine
+>>> classifier = pipeline(model="facebook/bart-large-mnli")
+>>> classifier(
+... "I have a problem with my iphone that needs to be resolved asap!!",
+... candidate_labels=["urgent", "not urgent", "phone", "tablet", "computer"],
+... )
+{'sequence': 'I have a problem with my iphone that needs to be resolved asap!!', 'labels': ['urgent', 'phone', 'computer', 'not urgent', 'tablet'], 'scores': [0.504, 0.479, 0.013, 0.003, 0.002]}
+```
+
+### 멀티모달 Pipeline[[multimodal-pipeline]]
+
+[`pipeline`]은 여러 모달리티(역주: 오디오, 비디오, 텍스트와 같은 데이터 형태)를 지원합니다. 예시로 시각적 질의응답(VQA; Visual Question Answering) 태스크는 텍스트와 이미지를 모두 사용합니다. 그 어떤 이미지 링크나 묻고 싶은 질문도 자유롭게 전달할 수 있습니다. 이미지는 URL 또는 로컬 경로의 형태로 전달해주세요.
+
+예를 들어 이 [거래명세서 사진](https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png)에서 거래명세서 번호를 묻고 싶다면,
+
+```py
+>>> from transformers import pipeline
+
+>>> vqa = pipeline(model="impira/layoutlm-document-qa")
+>>> vqa(
+... image="https://huggingface.co/spaces/impira/docquery/resolve/2359223c1837a7587402bda0f2643382a6eefeab/invoice.png",
+... question="What is the invoice number?",
+... )
+[{'score': 0.42514941096305847, 'answer': 'us-001', 'start': 16, 'end': 16}]
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/pipeline_webserver.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/pipeline_webserver.md
new file mode 100644
index 0000000000000000000000000000000000000000..b7d5366c57c4ef2edc7fb7505304299cf76317c2
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/pipeline_webserver.md
@@ -0,0 +1,144 @@
+
+
+# 웹 서버를 위한 파이프라인 사용하기[[using_pipelines_for_a_webserver]]
+
+
+추론 엔진을 만드는 것은 복잡한 주제이며, "최선의" 솔루션은 문제 공간에 따라 달라질 가능성이 높습니다. CPU 또는 GPU를 사용하는지에 따라 다르고 낮은 지연 시간을 원하는지, 높은 처리량을 원하는지, 다양한 모델을 지원할 수 있길 원하는지, 하나의 특정 모델을 고도로 최적화하길 원하는지 등에 따라 달라집니다. 이 주제를 해결하는 방법에는 여러 가지가 있으므로, 이 장에서 제시하는 것은 처음 시도해 보기에 좋은 출발점일 수는 있지만, 이 장을 읽는 여러분이 필요로 하는 최적의 솔루션은 아닐 수 있습니다.
+
+
+핵심적으로 이해해야 할 점은 [dataset](pipeline_tutorial#using-pipelines-on-a-dataset)를 다룰 때와 마찬가지로 반복자를 사용 가능하다는 것입니다. 왜냐하면, 웹 서버는 기본적으로 요청을 기다리고 들어오는 대로 처리하는 시스템이기 때문입니다.
+
+보통 웹 서버는 다양한 요청을 동시에 다루기 위해 매우 다중화된 구조(멀티 스레딩, 비동기 등)를 지니고 있습니다. 반면에, 파이프라인(대부분 파이프라인 안에 있는 모델)은 병렬처리에 그다지 좋지 않습니다. 왜냐하면 파이프라인은 많은 RAM을 차지하기 때문입니다. 따라서, 파이프라인이 실행 중이거나 계산 집약적인 작업 중일 때 모든 사용 가능한 리소스를 제공하는 것이 가장 좋습니다.
+
+이 문제를 우리는 웹 서버가 요청을 받고 보내는 가벼운 부하를 처리하고, 실제 작업을 처리하는 단일 스레드를 갖는 방법으로 해결할 것입니다. 이 예제는 `starlette` 라이브러리를 사용합니다.
+실제 프레임워크는 중요하지 않지만, 다른 프레임워크를 사용하는 경우 동일한 효과를 보기 위해선 코드를 조정하거나 변경해야 할 수 있습니다.
+
+`server.py`를 생성하세요:
+
+```py
+from starlette.applications import Starlette
+from starlette.responses import JSONResponse
+from starlette.routing import Route
+from transformers import pipeline
+import asyncio
+
+
+async def homepage(request):
+ payload = await request.body()
+ string = payload.decode("utf-8")
+ response_q = asyncio.Queue()
+ await request.app.model_queue.put((string, response_q))
+ output = await response_q.get()
+ return JSONResponse(output)
+
+
+async def server_loop(q):
+ pipe = pipeline(model="google-bert/bert-base-uncased")
+ while True:
+ (string, response_q) = await q.get()
+ out = pipe(string)
+ await response_q.put(out)
+
+
+app = Starlette(
+ routes=[
+ Route("/", homepage, methods=["POST"]),
+ ],
+)
+
+
+@app.on_event("startup")
+async def startup_event():
+ q = asyncio.Queue()
+ app.model_queue = q
+ asyncio.create_task(server_loop(q))
+```
+
+이제 다음 명령어로 실행시킬 수 있습니다:
+
+```bash
+uvicorn server:app
+```
+
+이제 쿼리를 날려볼 수 있습니다:
+
+```bash
+curl -X POST -d "test [MASK]" http://localhost:8000/
+#[{"score":0.7742936015129089,"token":1012,"token_str":".","sequence":"test."},...]
+```
+
+자, 이제 웹 서버를 만드는 방법에 대한 좋은 개념을 알게 되었습니다!
+
+중요한 점은 모델을 **한 번만** 가져온다는 것입니다. 따라서 웹 서버에는 모델의 사본이 없습니다. 이런 방식은 불필요한 RAM이 사용되지 않습니다. 그런 다음 큐 메커니즘을 사용하면, 다음과 같은
+동적 배치를 사용하기 위해 추론 전 단계에 몇 개의 항목을 축적하는 것과 같은 멋진 작업을 할 수 있습니다:
+
+
+코드는 의도적으로 가독성을 위해 의사 코드처럼 작성되었습니다!
+아래 코드를 작동시키기 전에 시스템 자원이 충분한지 확인하세요!
+
+
+```py
+(string, rq) = await q.get()
+strings = []
+queues = []
+while True:
+ try:
+ (string, rq) = await asyncio.wait_for(q.get(), timeout=0.001) # 1ms
+ except asyncio.exceptions.TimeoutError:
+ break
+ strings.append(string)
+ queues.append(rq)
+strings
+outs = pipe(strings, batch_size=len(strings))
+for rq, out in zip(queues, outs):
+ await rq.put(out)
+```
+
+다시 말씀 드리자면, 제안된 코드는 가독성을 위해 최적화되었으며, 최상의 코드는 아닙니다.
+첫째, 배치 크기 제한이 없으며 이는 일반적으로 좋은 방식이 아닙니다.
+둘째, 모든 큐 가져오기에서 타임아웃이 재설정되므로 추론을 실행하기 전에 1ms보다 훨씬 오래 기다릴 수 있습니다(첫 번째 요청을 그만큼 지연시킴).
+
+단일 1ms 길이의 데드라인을 두는 편이 더 좋습니다.
+
+이 방식을 사용하면 큐가 비어 있어도 항상 1ms를 기다리게 될 것입니다.
+큐에 아무것도 없을 때 추론을 원하는 경우에는 최선의 방법이 아닐 수 있습니다.
+하지만 배치 작업이 사용례에 따라 정말로 중요하다면 의미가 있을 수도 있습니다.
+다시 말하지만, 최상의 솔루션은 없습니다.
+
+## 고려해야 할 몇 가지 사항[[few_things_you_might want_to_consider]]
+
+### 에러 확인[[error_checking]]
+
+프로덕션 환경에서는 문제가 발생할 여지가 많습니다.
+메모리가 모자라거나, 공간이 부족하거나, 모델을 가져오는 데에 실패하거나, 쿼리가 잘못되었거나, 쿼리는 정확해도 모델 설정이 잘못되어 실행에 실패하는 등등 많은 경우가 존재합니다.
+
+일반적으로 서버가 사용자에게 오류를 출력하는 것이 좋으므로
+오류를 표시하기 위해 `try...except` 문을 많이 추가하는 것이 좋습니다.
+하지만 보안 상황에 따라 모든 오류를 표시하는 것은 보안상 위험할 수도 있다는 점을 명심해야합니다.
+
+### 서킷 브레이킹[[circuit_breaking]]
+
+웹 서버는 일반적으로 서킷 브레이킹을 수행할 때 더 나은 상황에 직면합니다.
+즉, 이는 서버가 쿼리를 무기한 기다리는 대신 과부하 상태일 때 적절한 오류를 반환하는 것을 의미합니다.
+서버가 매우 오랜 시간 동안 대기하거나 적당한 시간이 지난 후에 504 에러를 반환하는 대신 503 에러를 빠르게 반환하게 하는 것입니다.
+
+제안된 코드에는 단일 큐가 있으므로 구현하기가 비교적 쉽습니다.
+큐 크기를 확인하는 것은 웹 서버가 과부하 상항 하에 있을 때 에러를 반환하기 위한 가장 기초적인 작업입니다.
+
+### 메인 쓰레드 차단[[blocking_the_main_thread]]
+
+현재 PyTorch는 비동기 처리를 지원하지 않으며, 실행 중에는 메인 스레드가 차단됩니다.
+따라서 PyTorch를 별도의 스레드/프로세스에서 실행하도록 강제하는 것이 좋습니다.
+여기서는 이 작업이 수행되지 않았습니다. 왜냐하면 코드가 훨씬 더 복잡하기 때문입니다(주로 스레드, 비동기 처리, 큐가 서로 잘 맞지 않기 때문입니다).
+하지만 궁극적으로는 같은 작업을 수행하는 것입니다.
+
+단일 항목의 추론이 오래 걸린다면 (> 1초), 메인 쓰레드를 차단하는 것은 중요할 수 있습니다. 왜냐하면 이 경우 추론 중 모든 쿼리는 오류를 받기 전에 1초를 기다려야 하기 때문입니다.
+
+### 동적 배치[[dynamic_batching]]
+
+일반적으로, 배치 처리가 1개 항목을 한 번에 전달하는 것에 비해 반드시 성능 향상이 있는 것은 아닙니다(자세한 내용은 [`batching details`](./main_classes/pipelines#pipeline-batching)을 참고하세요).
+하지만 올바른 설정에서 사용하면 매우 효과적일 수 있습니다.
+API에는 기본적으로 속도 저하의 가능성이 매우 높기 때문에 동적 배치 처리가 없습니다.
+하지만 매우 큰 모델인 BLOOM 추론의 경우 동적 배치 처리는 모든 사람에게 적절한 경험을 제공하는 데 **필수**입니다.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/pr_checks.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/pr_checks.md
new file mode 100644
index 0000000000000000000000000000000000000000..1d155cd1fb9ddbc0f4c70b16faeba261b75f573f
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/pr_checks.md
@@ -0,0 +1,200 @@
+
+
+# Pull Request에 대한 검사 [[checks-on-a-pull-request]]
+
+🤗 Transformers에서 Pull Request를 열 때, 기존에 있는 것을 망가뜨리지 않는지 확인하기 위해 상당한 수의 검사가 실행됩니다. 이러한 검사는 다음과 같은 네 가지 유형으로 구성됩니다:
+- 일반적인 테스트
+- 문서 빌드
+- 코드 및 문서 스타일
+- 일반 저장소 일관성
+
+이 문서에서는 이러한 다양한 검사와 그 이유를 설명하고, PR에서 하나 이상의 검사가 실패한 경우 로컬에서 어떻게 디버그하는지 알아보겠습니다.
+
+참고로, 이러한 검사를 사용하려면 개발 설치가 필요합니다:
+
+```bash
+pip install transformers[dev]
+```
+
+또는 Transformers 저장소 내에 편집 가능한 설치가 필요합니다:
+
+```bash
+pip install -e .[dev]
+```
+
+Transformers의 선택적 종속성 수가 많이 늘어났기 때문에 개발 설치를 실패할 수도 있습니다. 개발 설치가 실패하는 경우, 작업 중인 Deep Learning 프레임워크 (PyTorch, TensorFlow 및/또는 Flax)를 설치하고 다음 명령을 실행하세요.
+
+```bash
+pip install transformers[quality]
+```
+
+편집 가능한 설치의 경우는 다음 명령을 실행하세요.
+
+```bash
+pip install -e .[quality]
+```
+
+
+## 테스트 [[tests]]
+
+`ci/circleci: run_tests_`로 시작하는 모든 작업은 Transformers 테스트 모음의 일부를 실행합니다. 이러한 작업은 특정 환경에서 일부 라이브러리에 중점을 둡니다. 예를 들어 `ci/circleci: run_tests_pipelines_tf`는 TensorFlow만 설치된 환경에서 파이프라인 테스트를 실행합니다.
+
+테스트 모듈에서 실제로 변경 사항이 없을 때 테스트를 실행하지 않기 위해, 테스트 모음의 일부만 실행됩니다. 라이브러리의 변경 전후에 대한 차이를 확인하기 위해 유틸리티가 실행되고, 해당 차이에 영향을 받는 테스트가 선택됩니다. 이 유틸리티는 로컬에서 다음과 같이 실행할 수 있습니다:
+
+```bash
+python utils/tests_fetcher.py
+```
+
+Transformers 저장소의 최상단에서 실행합니다. 이 유틸리티는 다음과 같은 작업을 수행합니다:
+
+1. 변경 사항이 있는 파일마다 변경 사항이 코드인지 주석 또는 문서 문자열인지 확인합니다. 실제 코드 변경이 있는 파일만 유지됩니다.
+2. 소스 코드 파일의 각 파일에 대해 재귀적으로 영향을 주는 모든 파일을 제공하는 내부 맵을 작성합니다. 모듈 B가 모듈 A를 가져오면 모듈 A는 모듈 B에 영향을 줍니다. 재귀적인 영향에는 각 모듈이 이전 모듈을 가져오는 모듈 체인이 필요합니다.
+3. 단계 1에서 수집한 파일에 이 맵을 적용하여 PR에 영향을 받는 모델 파일 목록을 얻습니다.
+4. 각 파일을 해당하는 테스트 파일에 매핑하고 실행할 테스트 목록을 가져옵니다.
+
+로컬에서 스크립트를 실행하면 단계 1, 3 및 4의 결과를 출력하여 실행되는 테스트를 알 수 있습니다. 스크립트는 또한 `test_list.txt`라는 파일을 생성하여 실행할 테스트 목록을 포함하며, 다음 명령으로 해당 테스트를 로컬에서 실행할 수 있습니다:
+
+```bash
+python -m pytest -n 8 --dist=loadfile -rA -s $(cat test_list.txt)
+```
+
+잘못된 사항이 누락되었을 경우, 전체 테스트 모음도 매일 실행됩니다.
+
+## 문서 빌드 [[documentation-build]]
+
+`build_pr_documentation` 작업은 문서를 빌드하고 미리 보기를 생성하여 PR이 병합된 후 모든 것이 제대로 보이는지 확인합니다. 로봇은 PR에 문서 미리보기 링크를 추가합니다. PR에서 만든 변경 사항은 자동으로 미리보기에 업데이트됩니다. 문서 빌드에 실패한 경우 **세부 정보**를 클릭하여 어디에서 문제가 발생했는지 확인할 수 있습니다. 오류는 주로 `toctree`에 누락된 파일과 같이 간단한 오류입니다.
+
+로컬에서 문서를 빌드하거나 미리 볼 경우, docs 폴더의 [`README.md`](https://github.com/huggingface/transformers/tree/main/docs)를 참조하세요.
+
+## 코드 및 문서 스타일 [[code-and-documentation-style]]
+
+`black`과 `ruff`를 사용하여 모든 소스 파일, 예제 및 테스트에 코드 형식을 적용합니다. 또한, `utils/style_doc.py`에서 문서 문자열과 `rst` 파일의 형식, 그리고 Transformers의 `__init__.py` 파일에서 실행되는 지연된 임포트의 순서에 대한 사용자 정의 도구가 있습니다. 이 모든 것은 다음을 실행함으로써 실행할 수 있습니다:
+
+```bash
+make style
+```
+
+CI는 이러한 사항이 `ci/circleci: check_code_quality` 검사 내에서 적용되었는지 확인합니다. 또한 `ruff`도 실행되며, 정의되지 않은 변수나 사용되지 않은 변수를 발견하면 경고합니다. 이 검사를 로컬에서 실행하려면 다음을 사용하세요:
+
+```bash
+make quality
+```
+
+이 작업은 많은 시간이 소요될 수 있으므로 현재 브랜치에서 수정한 파일에 대해서만 동일한 작업을 실행하려면 다음을 실행하세요.
+
+```bash
+make fixup
+```
+
+이 명령은 현재 브랜치에서 수정한 파일에 대한 모든 추가적인 검사도 실행합니다. 이제 이들을 살펴보겠습니다.
+
+## 저장소 일관성 [[repository-consistency]]
+
+이는 PR이 저장소를 정상적인 상태로 유지하는지 확인하는 모든 테스트를 모은 것이며, `ci/circleci: check_repository_consistency` 검사에서 수행됩니다. 다음을 실행함으로써 로컬에서 이 검사를 실행할 수 있습니다.
+
+```bash
+make repo-consistency
+```
+
+이 검사는 다음을 확인합니다.
+
+- init에 추가된 모든 객체가 문서화되었는지 (`utils/check_repo.py`에서 수행)
+- `__init__.py` 파일의 두 섹션에 동일한 내용이 있는지 (`utils/check_inits.py`에서 수행)
+- 다른 모듈에서 복사된 코드가 원본과 일치하는지 (`utils/check_copies.py`에서 수행)
+- 모든 구성 클래스에 docstring에 언급된 유효한 체크포인트가 적어도 하나 있는지 (`utils/check_config_docstrings.py`에서 수행)
+- 모든 구성 클래스가 해당하는 모델링 파일에서 사용되는 속성만 포함하고 있는지 (`utils/check_config_attributes.py`에서 수행)
+- README와 문서 인덱스의 번역이 메인 README와 동일한 모델 목록을 가지고 있는지 (`utils/check_copies.py`에서 수행)
+- 문서의 자동 생성된 테이블이 최신 상태인지 (`utils/check_table.py`에서 수행)
+- 라이브러리에는 선택적 종속성이 설치되지 않았더라도 모든 객체가 사용 가능한지 (`utils/check_dummies.py`에서 수행)
+
+이러한 검사가 실패하는 경우, 처음 두 가지 항목은 수동으로 수정해야 하며, 나머지 네 가지 항목은 다음 명령을 실행하여 자동으로 수정할 수 있습니다.
+
+```bash
+make fix-copies
+```
+
+추가적인 검사는 새로운 모델을 추가하는 PR에 대한 것으로, 주로 다음과 같습니다:
+
+- 추가된 모든 모델이 Auto-mapping에 있는지 (`utils/check_repo.py`에서 수행)
+
+- 모든 모델이 올바르게 테스트되었는지 (`utils/check_repo.py`에서 수행)
+
+
+
+### 복사본 확인 [[check-copies]]
+
+Transformers 라이브러리는 모델 코드에 대해 매우 완고하며, 각 모델은 다른 모델에 의존하지 않고 완전히 단일 파일로 구현되어야 합니다. 이렇게 하기 위해 특정 모델의 코드 복사본이 원본과 일관된 상태로 유지되는지 확인하는 메커니즘을 추가했습니다. 따라서 버그 수정이 필요한 경우 다른 모델에 영향을 주는 모든 모델을 볼 수 있으며 수정을 적용할지 수정된 사본을 삭제할지 선택할 수 있습니다.
+
+
+
+파일이 다른 파일의 완전한 사본인 경우 해당 파일을 `utils/check_copies.py`의 `FULL_COPIES` 상수에 등록해야 합니다.
+
+
+
+이 메커니즘은 `# Copied from xxx` 형식의 주석을 기반으로 합니다. `xxx`에는 아래에 복사되는 클래스 또는 함수의 전체 경로가 포함되어야 합니다. 예를 들어 `RobertaSelfOutput`은 `BertSelfOutput` 클래스의 복사본입니다. 따라서 [여기](https://github.com/huggingface/transformers/blob/2bd7a27a671fd1d98059124024f580f8f5c0f3b5/src/transformers/models/roberta/modeling_roberta.py#L289)에서 주석이 있습니다:
+
+
+```py
+# Copied from transformers.models.bert.modeling_bert.BertSelfOutput
+```
+
+클래스 전체에 수정을 적용하는 대신에 복사본과 관련있는 메서드에 적용할 수도 있습니다. 예를 들어 [여기](https://github.com/huggingface/transformers/blob/2bd7a27a671fd1d98059124024f580f8f5c0f3b5/src/transformers/models/roberta/modeling_roberta.py#L598)에서 `RobertaPreTrainedModel._init_weights`가 `BertPreTrainedModel`의 동일한 메서드에서 복사된 것을 볼 수 있으며 해당 주석이 있습니다:
+
+```py
+# Copied from transformers.models.bert.modeling_bert.BertPreTrainedModel._init_weights
+```
+
+복사본이 이름만 다른 경우가 있습니다: 예를 들어 `RobertaAttention`에서 `BertSelfAttention` 대신 `RobertaSelfAttention`을 사용하지만 그 외에는 코드가 완전히 동일합니다: 이 때 `# Copied from`은 `Copied from xxx with foo->bar`와 같은 간단한 문자열 대체를 지원합니다. 이는 모든 `foo` 인스턴스를 `bar`로 바꿔서 코드를 복사합니다. [여기](https://github.com/huggingface/transformers/blob/2bd7a27a671fd1d98059124024f580f8f5c0f3b5/src/transformers/models/roberta/modeling_roberta.py#L304C1-L304C86)에서 어떻게 사용되는지 볼 수 있습니다:
+
+```py
+# Copied from transformers.models.bert.modeling_bert.BertAttention with Bert->Roberta
+```
+
+화살표 주변에는 공백이 없어야 합니다(공백이 대체 패턴의 일부인 경우는 예외입니다).
+
+대체 패턴을 쉼표로 구분하여 여러 패턴을 추가할 수 있습니다. 예를 들어 `CamemberForMaskedLM`은 두 가지 대체 사항을 가진 `RobertaForMaskedLM`의 복사본입니다: `Roberta`를 `Camembert`로 대체하고 `ROBERTA`를 `CAMEMBERT`로 대체합니다. [여기](https://github.com/huggingface/transformers/blob/15082a9dc6950ecae63a0d3e5060b2fc7f15050a/src/transformers/models/camembert/modeling_camembert.py#L929)에서 이것이 주석으로 어떻게 구현되었는지 확인할 수 있습니다:
+
+```py
+# Copied from transformers.models.roberta.modeling_roberta.RobertaForMaskedLM with Roberta->Camembert, ROBERTA->CAMEMBERT
+```
+
+순서가 중요한 경우(이전 수정과 충돌할 수 있는 경우) 수정은 왼쪽에서 오른쪽으로 실행됩니다.
+
+
+
+새 변경이 서식을 변경하는 경우(짧은 이름을 매우 긴 이름으로 바꾸는 경우) 자동 서식 지정기를 적용한 후 복사본이 검사됩니다.
+
+
+
+패턴의 대소문자가 다른 경우(대문자와 소문자가 혼용된 대체 양식) `all-casing` 옵션을 추가하는 방법도 있습니다. [여기](https://github.com/huggingface/transformers/blob/15082a9dc6950ecae63a0d3e5060b2fc7f15050a/src/transformers/models/mobilebert/modeling_mobilebert.py#L1237)에서 `MobileBertForSequenceClassification`에서 사용된 예시를 볼 수 있습니다:
+
+```py
+# Copied from transformers.models.bert.modeling_bert.BertForSequenceClassification with Bert->MobileBert all-casing
+```
+
+이 경우, 코드는 다음과 같이 복사됩니다:
+- `MobileBert`에서 `Bert`로(예: `MobileBertModel`을 init에서 사용할 때)
+- `mobilebert`에서 `bert`로(예: `self.mobilebert`를 정의할 때)
+- `MOBILEBERT`에서 `BERT`로(`MOBILEBERT_INPUTS_DOCSTRING` 상수에서)
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/preprocessing.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/preprocessing.md
new file mode 100644
index 0000000000000000000000000000000000000000..4466b63585723d49a5165135c40ec287d25ff907
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/preprocessing.md
@@ -0,0 +1,539 @@
+
+
+# 전처리[[preprocess]]
+
+[[open-in-colab]]
+
+모델을 훈련하려면 데이터 세트를 모델에 맞는 입력 형식으로 전처리해야 합니다. 텍스트, 이미지 또는 오디오인지 관계없이 데이터를 텐서 배치로 변환하고 조립할 필요가 있습니다. 🤗 Transformers는 모델에 대한 데이터를 준비하는 데 도움이 되는 일련의 전처리 클래스를 제공합니다. 이 튜토리얼에서는 다음 내용을 배울 수 있습니다:
+
+* 텍스트는 [Tokenizer](./main_classes/tokenizer)를 사용하여 토큰 시퀀스로 변환하고 토큰의 숫자 표현을 만든 후 텐서로 조립합니다.
+* 음성 및 오디오는 [Feature extractor](./main_classes/feature_extractor)를 사용하여 오디오 파형에서 시퀀스 특성을 파악하여 텐서로 변환합니다.
+* 이미지 입력은 [ImageProcessor](./main_classes/image)을 사용하여 이미지를 텐서로 변환합니다.
+* 멀티모달 입력은 [Processor](./main_classes/processors)을 사용하여 토크나이저와 특성 추출기 또는 이미지 프로세서를 결합합니다.
+
+
+
+`AutoProcessor`는 **언제나** 작동하여 토크나이저, 이미지 프로세서, 특성 추출기 또는 프로세서 등 사용 중인 모델에 맞는 클래스를 자동으로 선택합니다.
+
+
+
+시작하기 전에 🤗 Datasets를 설치하여 실험에 사용할 데이터를 불러올 수 있습니다:
+
+```bash
+pip install datasets
+```
+
+## 자연어처리[[natural-language-processing]]
+
+
+
+텍스트 데이터를 전처리하기 위한 기본 도구는 [tokenizer](main_classes/tokenizer)입니다. 토크나이저는 일련의 규칙에 따라 텍스트를 *토큰*으로 나눕니다. 토큰은 숫자로 변환되고 텐서는 모델 입력이 됩니다. 모델에 필요한 추가 입력은 토크나이저에 의해 추가됩니다.
+
+
+
+사전훈련된 모델을 사용할 계획이라면 모델과 함께 사전훈련된 토크나이저를 사용하는 것이 중요합니다. 이렇게 하면 텍스트가 사전훈련 말뭉치와 동일한 방식으로 분할되고 사전훈련 중에 동일한 해당 토큰-인덱스 쌍(일반적으로 *vocab*이라고 함)을 사용합니다.
+
+
+
+시작하려면 [`AutoTokenizer.from_pretrained`] 메소드를 사용하여 사전훈련된 토크나이저를 불러오세요. 모델과 함께 사전훈련된 *vocab*을 다운로드합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
+```
+
+그 다음으로 텍스트를 토크나이저에 넣어주세요:
+
+```py
+>>> encoded_input = tokenizer("Do not meddle in the affairs of wizards, for they are subtle and quick to anger.")
+>>> print(encoded_input)
+{'input_ids': [101, 2079, 2025, 19960, 10362, 1999, 1996, 3821, 1997, 16657, 1010, 2005, 2027, 2024, 11259, 1998, 4248, 2000, 4963, 1012, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+토크나이저는 세 가지 중요한 항목을 포함한 딕셔너리를 반환합니다:
+
+* [input_ids](glossary#input-ids)는 문장의 각 토큰에 해당하는 인덱스입니다.
+* [attention_mask](glossary#attention-mask)는 토큰을 처리해야 하는지 여부를 나타냅니다.
+* [token_type_ids](glossary#token-type-ids)는 두 개 이상의 시퀀스가 있을 때 토큰이 속한 시퀀스를 식별합니다.
+
+`input_ids`를 디코딩하여 입력을 반환합니다:
+
+```py
+>>> tokenizer.decode(encoded_input["input_ids"])
+'[CLS] Do not meddle in the affairs of wizards, for they are subtle and quick to anger. [SEP]'
+```
+
+토크나이저가 두 개의 특수한 토큰(분류 토큰 `CLS`와 분할 토큰 `SEP`)을 문장에 추가했습니다.
+모든 모델에 특수한 토큰이 필요한 것은 아니지만, 필요하다면 토크나이저가 자동으로 추가합니다.
+
+전처리할 문장이 여러 개 있는 경우에는 리스트로 토크나이저에 전달합니다:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_inputs = tokenizer(batch_sentences)
+>>> print(encoded_inputs)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1]]}
+```
+
+### 패딩[[pad]]
+
+모델 입력인 텐서는 모양이 균일해야 하지만, 문장의 길이가 항상 같지는 않기 때문에 문제가 될 수 있습니다. 패딩은 짧은 문장에 특수한 *패딩 토큰*을 추가하여 텐서를 직사각형 모양이 되도록 하는 전략입니다.
+
+`padding` 매개변수를 `True`로 설정하여 배치 내의 짧은 시퀀스를 가장 긴 시퀀스에 맞춰 패딩합니다.
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True)
+>>> print(encoded_input)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
+```
+
+길이가 짧은 첫 문장과 세 번째 문장이 이제 `0`으로 채워졌습니다.
+
+### 잘라내기[[truncation]]
+
+한편, 때로는 시퀀스가 모델에서 처리하기에 너무 길 수도 있습니다. 이 경우, 시퀀스를 더 짧게 줄일 필요가 있습니다.
+
+모델에서 허용하는 최대 길이로 시퀀스를 자르려면 `truncation` 매개변수를 `True`로 설정하세요:
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True)
+>>> print(encoded_input)
+{'input_ids': [[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'token_type_ids': [[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]],
+ 'attention_mask': [[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]]}
+```
+
+
+
+다양한 패딩과 잘라내기 인수에 대해 더 알아보려면 [패딩과 잘라내기](./pad_truncation) 개념 가이드를 확인해보세요.
+
+
+
+### 텐서 만들기[[build-tensors]]
+
+마지막으로, 토크나이저가 모델에 공급되는 실제 텐서를 반환하도록 합니다.
+
+`return_tensors` 매개변수를 PyTorch의 경우 `pt`, TensorFlow의 경우 `tf`로 설정하세요:
+
+
+
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True, return_tensors="pt")
+>>> print(encoded_input)
+{'input_ids': tensor([[101, 1252, 1184, 1164, 1248, 6462, 136, 102, 0, 0, 0, 0, 0, 0, 0],
+ [101, 1790, 112, 189, 1341, 1119, 3520, 1164, 1248, 6462, 117, 21902, 1643, 119, 102],
+ [101, 1327, 1164, 5450, 23434, 136, 102, 0, 0, 0, 0, 0, 0, 0, 0]]),
+ 'token_type_ids': tensor([[0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0]]),
+ 'attention_mask': tensor([[1, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0],
+ [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1],
+ [1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 0, 0, 0, 0]])}
+```
+
+
+```py
+>>> batch_sentences = [
+... "But what about second breakfast?",
+... "Don't think he knows about second breakfast, Pip.",
+... "What about elevensies?",
+... ]
+>>> encoded_input = tokenizer(batch_sentences, padding=True, truncation=True, return_tensors="tf")
+>>> print(encoded_input)
+{'input_ids': ,
+ 'token_type_ids': ,
+ 'attention_mask': }
+```
+
+
+
+## 오디오[[audio]]
+
+오디오 작업은 모델에 맞는 데이터 세트를 준비하기 위해 [특성 추출기](main_classes/feature_extractor)가 필요합니다. 특성 추출기는 원시 오디오 데이터에서 특성를 추출하고 이를 텐서로 변환하는 것이 목적입니다.
+
+오디오 데이터 세트에 특성 추출기를 사용하는 방법을 보기 위해 [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) 데이터 세트를 가져오세요. (데이터 세트를 가져오는 방법은 🤗 [데이터 세트 튜토리얼](https://huggingface.co/docs/datasets/load_hub)에서 자세히 설명하고 있습니다.)
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train")
+```
+
+`audio` 열의 첫 번째 요소에 접근하여 입력을 살펴보세요. `audio` 열을 호출하면 오디오 파일을 자동으로 가져오고 리샘플링합니다.
+
+```py
+>>> dataset[0]["audio"]
+{'array': array([ 0. , 0.00024414, -0.00024414, ..., -0.00024414,
+ 0. , 0. ], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~JOINT_ACCOUNT/602ba55abb1e6d0fbce92065.wav',
+ 'sampling_rate': 8000}
+```
+
+이렇게 하면 세 가지 항목이 반환됩니다:
+
+* `array`는 1D 배열로 가져와서 (필요한 경우) 리샘플링된 음성 신호입니다.
+* `path`는 오디오 파일의 위치를 가리킵니다.
+* `sampling_rate`는 음성 신호에서 초당 측정되는 데이터 포인트 수를 나타냅니다.
+
+이 튜토리얼에서는 [Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base) 모델을 사용합니다. 모델 카드를 보면 Wav2Vec2가 16kHz 샘플링된 음성 오디오를 기반으로 사전훈련된 것을 알 수 있습니다.
+모델을 사전훈련하는 데 사용된 데이터 세트의 샘플링 레이트와 오디오 데이터의 샘플링 레이트가 일치해야 합니다. 데이터의 샘플링 레이트가 다르면 데이터를 리샘플링해야 합니다.
+
+1. 🤗 Datasets의 [`~datasets.Dataset.cast_column`] 메소드를 사용하여 샘플링 레이트를 16kHz로 업샘플링하세요:
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16_000))
+```
+
+2. 오디오 파일을 리샘플링하기 위해 `audio` 열을 다시 호출합니다:
+
+```py
+>>> dataset[0]["audio"]
+{'array': array([ 2.3443763e-05, 2.1729663e-04, 2.2145823e-04, ...,
+ 3.8356509e-05, -7.3497440e-06, -2.1754686e-05], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~JOINT_ACCOUNT/602ba55abb1e6d0fbce92065.wav',
+ 'sampling_rate': 16000}
+```
+
+다음으로, 입력을 정규화하고 패딩할 특성 추출기를 가져오세요. 텍스트 데이터의 경우, 더 짧은 시퀀스에 대해 `0`이 추가됩니다. 오디오 데이터에도 같은 개념이 적용됩니다.
+특성 추출기는 배열에 `0`(묵음으로 해석)을 추가합니다.
+
+[`AutoFeatureExtractor.from_pretrained`]를 사용하여 특성 추출기를 가져오세요:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base")
+```
+
+오디오 `array`를 특성 추출기에 전달하세요. 또한, 발생할 수 있는 조용한 오류(silent errors)를 더 잘 디버깅할 수 있도록 특성 추출기에 `sampling_rate` 인수를 추가하는 것을 권장합니다.
+
+```py
+>>> audio_input = [dataset[0]["audio"]["array"]]
+>>> feature_extractor(audio_input, sampling_rate=16000)
+{'input_values': [array([ 3.8106556e-04, 2.7506407e-03, 2.8015103e-03, ...,
+ 5.6335266e-04, 4.6588284e-06, -1.7142107e-04], dtype=float32)]}
+```
+
+토크나이저와 마찬가지로 배치 내에서 가변적인 시퀀스를 처리하기 위해 패딩 또는 잘라내기를 적용할 수 있습니다. 이 두 개의 오디오 샘플의 시퀀스 길이를 확인해보세요:
+
+```py
+>>> dataset[0]["audio"]["array"].shape
+(173398,)
+
+>>> dataset[1]["audio"]["array"].shape
+(106496,)
+```
+
+오디오 샘플의 길이가 동일하도록 데이터 세트를 전처리하는 함수를 만드세요. 최대 샘플 길이를 지정하면 특성 추출기가 해당 길이에 맞춰 시퀀스를 패딩하거나 잘라냅니다:
+
+```py
+>>> def preprocess_function(examples):
+... audio_arrays = [x["array"] for x in examples["audio"]]
+... inputs = feature_extractor(
+... audio_arrays,
+... sampling_rate=16000,
+... padding=True,
+... max_length=100000,
+... truncation=True,
+... )
+... return inputs
+```
+
+`preprocess_function`을 데이터 세트의 처음 예시 몇 개에 적용해보세요:
+
+```py
+>>> processed_dataset = preprocess_function(dataset[:5])
+```
+
+이제 샘플 길이가 모두 같고 지정된 최대 길이에 맞게 되었습니다. 드디어 전처리된 데이터 세트를 모델에 전달할 수 있습니다!
+
+```py
+>>> processed_dataset["input_values"][0].shape
+(100000,)
+
+>>> processed_dataset["input_values"][1].shape
+(100000,)
+```
+
+## 컴퓨터 비전[[computer-vision]]
+
+컴퓨터 비전 작업의 경우, 모델에 대한 데이터 세트를 준비하기 위해 [이미지 프로세서](main_classes/image_processor)가 필요합니다.
+이미지 전처리는 이미지를 모델이 예상하는 입력으로 변환하는 여러 단계로 이루어집니다.
+이러한 단계에는 크기 조정, 정규화, 색상 채널 보정, 이미지의 텐서 변환 등이 포함됩니다.
+
+
+
+이미지 전처리는 이미지 증강 기법을 몇 가지 적용한 뒤에 할 수도 있습니다.
+이미지 전처리 및 이미지 증강은 모두 이미지 데이터를 변형하지만, 서로 다른 목적을 가지고 있습니다:
+
+* 이미지 증강은 과적합(over-fitting)을 방지하고 모델의 견고함(resiliency)을 높이는 데 도움이 되는 방식으로 이미지를 수정합니다.
+밝기와 색상 조정, 자르기, 회전, 크기 조정, 확대/축소 등 다양한 방법으로 데이터를 증강할 수 있습니다.
+그러나 증강으로 이미지의 의미가 바뀌지 않도록 주의해야 합니다.
+* 이미지 전처리는 이미지가 모델이 예상하는 입력 형식과 일치하도록 보장합니다.
+컴퓨터 비전 모델을 미세 조정할 때 이미지는 모델이 초기에 훈련될 때와 정확히 같은 방식으로 전처리되어야 합니다.
+
+이미지 증강에는 원하는 라이브러리를 무엇이든 사용할 수 있습니다. 이미지 전처리에는 모델과 연결된 `ImageProcessor`를 사용합니다.
+
+
+
+[food101](https://huggingface.co/datasets/food101) 데이터 세트를 가져와서 컴퓨터 비전 데이터 세트에서 이미지 프로세서를 어떻게 사용하는지 알아보세요.
+데이터 세트를 불러오는 방법은 🤗 [데이터 세트 튜토리얼](https://huggingface.co/docs/datasets/load_hub)을 참고하세요.
+
+
+
+데이터 세트가 상당히 크기 때문에 🤗 Datasets의 `split` 매개변수를 사용하여 훈련 세트에서 작은 샘플만 가져오세요!
+
+
+
+```py
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("food101", split="train[:100]")
+```
+
+다음으로, 🤗 Datasets의 [`image`](https://huggingface.co/docs/datasets/package_reference/main_classes?highlight=image#datasets.Image)로 이미지를 확인해보세요:
+
+```py
+>>> dataset[0]["image"]
+```
+
+
+
+
+
+[`AutoImageProcessor.from_pretrained`]로 이미지 프로세서를 가져오세요:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+```
+
+먼저 이미지 증강 단계를 추가해 봅시다. 아무 라이브러리나 사용해도 괜찮지만, 이번 튜토리얼에서는 torchvision의 [`transforms`](https://pytorch.org/vision/stable/transforms.html) 모듈을 사용하겠습니다.
+다른 데이터 증강 라이브러리를 사용해보고 싶다면, [Albumentations](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification_albumentations.ipynb) 또는 [Kornia notebooks](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification_kornia.ipynb)에서 어떻게 사용하는지 배울 수 있습니다.
+
+1. [`Compose`](https://pytorch.org/vision/master/generated/torchvision.transforms.Compose.html)로 [`RandomResizedCrop`](https://pytorch.org/vision/main/generated/torchvision.transforms.RandomResizedCrop.html)와 [`ColorJitter`](https://pytorch.org/vision/main/generated/torchvision.transforms.ColorJitter.html) 등 변환을 몇 가지 연결하세요.
+참고로 크기 조정에 필요한 이미지의 크기 요구사항은 `image_processor`에서 가져올 수 있습니다.
+일부 모델은 정확한 높이와 너비를 요구하지만, 제일 짧은 변의 길이(`shortest_edge`)만 정의된 모델도 있습니다.
+
+```py
+>>> from torchvision.transforms import RandomResizedCrop, ColorJitter, Compose
+
+>>> size = (
+... image_processor.size["shortest_edge"]
+... if "shortest_edge" in image_processor.size
+... else (image_processor.size["height"], image_processor.size["width"])
+... )
+
+>>> _transforms = Compose([RandomResizedCrop(size), ColorJitter(brightness=0.5, hue=0.5)])
+```
+
+2. 모델은 입력으로 [`pixel_values`](model_doc/visionencoderdecoder#transformers.VisionEncoderDecoderModel.forward.pixel_values)를 받습니다.
+`ImageProcessor`는 이미지 정규화 및 적절한 텐서 생성을 처리할 수 있습니다.
+배치 이미지에 대한 이미지 증강 및 이미지 전처리를 결합하고 `pixel_values`를 생성하는 함수를 만듭니다:
+
+```py
+>>> def transforms(examples):
+... images = [_transforms(img.convert("RGB")) for img in examples["image"]]
+... examples["pixel_values"] = image_processor(images, do_resize=False, return_tensors="pt")["pixel_values"]
+... return examples
+```
+
+
+
+위의 예에서는 이미지 증강 중에 이미지 크기를 조정했기 때문에 `do_resize=False`로 설정하고, 해당 `image_processor`에서 `size` 속성을 활용했습니다.
+이미지 증강 중에 이미지 크기를 조정하지 않은 경우 이 매개변수를 생략하세요.
+기본적으로는 `ImageProcessor`가 크기 조정을 처리합니다.
+
+증강 변환 과정에서 이미지를 정규화하려면 `image_processor.image_mean` 및 `image_processor.image_std` 값을 사용하세요.
+
+
+
+3. 🤗 Datasets의 [`set_transform`](https://huggingface.co/docs/datasets/process#format-transform)를 사용하여 실시간으로 변환을 적용합니다:
+
+```py
+>>> dataset.set_transform(transforms)
+```
+
+4. 이제 이미지에 접근하면 이미지 프로세서가 `pixel_values`를 추가한 것을 알 수 있습니다.
+드디어 처리된 데이터 세트를 모델에 전달할 수 있습니다!
+
+```py
+>>> dataset[0].keys()
+```
+
+다음은 변형이 적용된 후의 이미지입니다. 이미지가 무작위로 잘려나갔고 색상 속성이 다릅니다.
+
+```py
+>>> import numpy as np
+>>> import matplotlib.pyplot as plt
+
+>>> img = dataset[0]["pixel_values"]
+>>> plt.imshow(img.permute(1, 2, 0))
+```
+
+
+
+
+
+
+
+`ImageProcessor`는 객체 감지, 시맨틱 세그멘테이션(semantic segmentation), 인스턴스 세그멘테이션(instance segmentation), 파놉틱 세그멘테이션(panoptic segmentation)과 같은 작업에 대한 후처리 방법을 제공합니다.
+이러한 방법은 모델의 원시 출력을 경계 상자나 세그멘테이션 맵과 같은 의미 있는 예측으로 변환해줍니다.
+
+
+
+### 패딩[[pad]]
+
+예를 들어, [DETR](./model_doc/detr)와 같은 경우에는 모델이 훈련할 때 크기 조정 증강을 적용합니다.
+이로 인해 배치 내 이미지 크기가 달라질 수 있습니다.
+[`DetrImageProcessor`]의 [`DetrImageProcessor.pad`]를 사용하고 사용자 정의 `collate_fn`을 정의해서 배치 이미지를 처리할 수 있습니다.
+
+```py
+>>> def collate_fn(batch):
+... pixel_values = [item["pixel_values"] for item in batch]
+... encoding = image_processor.pad(pixel_values, return_tensors="pt")
+... labels = [item["labels"] for item in batch]
+... batch = {}
+... batch["pixel_values"] = encoding["pixel_values"]
+... batch["pixel_mask"] = encoding["pixel_mask"]
+... batch["labels"] = labels
+... return batch
+```
+
+## 멀티모달[[multimodal]]
+
+멀티모달 입력이 필요한 작업의 경우, 모델에 데이터 세트를 준비하기 위한 [프로세서](main_classes/processors)가 필요합니다.
+프로세서는 토크나이저와 특성 추출기와 같은 두 가지 처리 객체를 결합합니다.
+
+[LJ Speech](https://huggingface.co/datasets/lj_speech) 데이터 세트를 가져와서 자동 음성 인식(ASR)을 위한 프로세서를 사용하는 방법을 확인하세요.
+(데이터 세트를 가져오는 방법에 대한 자세한 내용은 🤗 [데이터 세트 튜토리얼](https://huggingface.co/docs/datasets/load_hub)에서 볼 수 있습니다.)
+
+```py
+>>> from datasets import load_dataset
+
+>>> lj_speech = load_dataset("lj_speech", split="train")
+```
+
+자동 음성 인식(ASR)에서는 `audio`와 `text`에만 집중하면 되므로, 다른 열들은 제거할 수 있습니다:
+
+```py
+>>> lj_speech = lj_speech.map(remove_columns=["file", "id", "normalized_text"])
+```
+
+이제 `audio`와 `text`열을 살펴보세요:
+
+```py
+>>> lj_speech[0]["audio"]
+{'array': array([-7.3242188e-04, -7.6293945e-04, -6.4086914e-04, ...,
+ 7.3242188e-04, 2.1362305e-04, 6.1035156e-05], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/917ece08c95cf0c4115e45294e3cd0dee724a1165b7fc11798369308a465bd26/LJSpeech-1.1/wavs/LJ001-0001.wav',
+ 'sampling_rate': 22050}
+
+>>> lj_speech[0]["text"]
+'Printing, in the only sense with which we are at present concerned, differs from most if not from all the arts and crafts represented in the Exhibition'
+```
+
+기존에 사전훈련된 모델에서 사용된 데이터 세트와 새로운 오디오 데이터 세트의 샘플링 레이트를 일치시키기 위해 오디오 데이터 세트의 샘플링 레이트를 [리샘플링](preprocessing#audio)해야 합니다!
+
+```py
+>>> lj_speech = lj_speech.cast_column("audio", Audio(sampling_rate=16_000))
+```
+
+[`AutoProcessor.from_pretrained`]로 프로세서를 가져오세요:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base-960h")
+```
+
+1. `array`에 들어 있는 오디오 데이터를 `input_values`로 변환하고 `text`를 토큰화하여 `labels`로 변환하는 함수를 만듭니다.
+모델의 입력은 다음과 같습니다:
+
+```py
+>>> def prepare_dataset(example):
+... audio = example["audio"]
+
+... example.update(processor(audio=audio["array"], text=example["text"], sampling_rate=16000))
+
+... return example
+```
+
+2. 샘플을 `prepare_dataset` 함수에 적용하세요:
+
+```py
+>>> prepare_dataset(lj_speech[0])
+```
+
+이제 프로세서가 `input_values`와 `labels`를 추가하고, 샘플링 레이트도 올바르게 16kHz로 다운샘플링했습니다.
+드디어 처리된 데이터 세트를 모델에 전달할 수 있습니다!
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/awq.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/awq.md
new file mode 100644
index 0000000000000000000000000000000000000000..3855b42a73525ab9bebbb15d37df9070f1ffa143
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/awq.md
@@ -0,0 +1,233 @@
+
+
+# AWQ [[awq]]
+
+
+
+이 [노트북](https://colab.research.google.com/drive/1HzZH89yAXJaZgwJDhQj9LqSBux932BvY) 으로 AWQ 양자화를 실습해보세요 !
+
+
+
+[Activation-aware Weight Quantization (AWQ)](https://hf.co/papers/2306.00978)은 모델의 모든 가중치를 양자화하지 않고, LLM 성능에 중요한 가중치를 유지합니다. 이로써 4비트 정밀도로 모델을 실행해도 성능 저하 없이 양자화 손실을 크게 줄일 수 있습니다.
+
+AWQ 알고리즘을 사용하여 모델을 양자화할 수 있는 여러 라이브러리가 있습니다. 예를 들어 [llm-awq](https://github.com/mit-han-lab/llm-awq), [autoawq](https://github.com/casper-hansen/AutoAWQ) , [optimum-intel](https://huggingface.co/docs/optimum/main/en/intel/optimization_inc) 등이 있습니다. Transformers는 llm-awq, autoawq 라이브러리를 이용해 양자화된 모델을 가져올 수 있도록 지원합니다. 이 가이드에서는 autoawq로 양자화된 모델을 가져오는 방법을 보여드리나, llm-awq로 양자화된 모델의 경우도 유사한 절차를 따릅니다.
+
+autoawq가 설치되어 있는지 확인하세요:
+
+```bash
+pip install autoawq
+```
+
+AWQ 양자화된 모델은 해당 모델의 [config.json](https://huggingface.co/TheBloke/zephyr-7B-alpha-AWQ/blob/main/config.json) 파일의 `quantization_config` 속성을 통해 식별할 수 있습니다.:
+
+```json
+{
+ "_name_or_path": "/workspace/process/huggingfaceh4_zephyr-7b-alpha/source",
+ "architectures": [
+ "MistralForCausalLM"
+ ],
+ ...
+ ...
+ ...
+ "quantization_config": {
+ "quant_method": "awq",
+ "zero_point": true,
+ "group_size": 128,
+ "bits": 4,
+ "version": "gemm"
+ }
+}
+```
+
+양자화된 모델은 [`~PreTrainedModel.from_pretrained`] 메서드를 사용하여 가져옵니다. 모델을 CPU에 가져왔다면, 먼저 모델을 GPU 장치로 옮겨야 합니다. `device_map` 파라미터를 사용하여 모델을 배치할 위치를 지정하세요:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "TheBloke/zephyr-7B-alpha-AWQ"
+model = AutoModelForCausalLM.from_pretrained(model_id, device_map="cuda:0")
+```
+
+AWQ 양자화 모델을 가져오면 자동으로 성능상의 이유로 인해 가중치들의 기본값이 fp16으로 설정됩니다. 가중치를 다른 형식으로 가져오려면, `torch_dtype` 파라미터를 사용하세요:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_id = "TheBloke/zephyr-7B-alpha-AWQ"
+model = AutoModelForCausalLM.from_pretrained(model_id, torch_dtype=torch.float32)
+```
+
+추론을 더욱 가속화하기 위해 AWQ 양자화와 [FlashAttention-2](../perf_infer_gpu_one#flashattention-2) 를 결합 할 수 있습니다:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("TheBloke/zephyr-7B-alpha-AWQ", attn_implementation="flash_attention_2", device_map="cuda:0")
+```
+
+## 퓨즈된 모듈 [[fused-modules]]
+
+퓨즈된 모듈은 정확도와 성능을 개선합니다. 퓨즈된 모듈은 [Llama](https://huggingface.co/meta-llama) 아키텍처와 [Mistral](https://huggingface.co/mistralai/Mistral-7B-v0.1) 아키텍처의 AWQ모듈에 기본적으로 지원됩니다. 그러나 지원되지 않는 아키텍처에 대해서도 AWQ 모듈을 퓨즈할 수 있습니다.
+
+
+
+퓨즈된 모듈은 FlashAttention-2와 같은 다른 최적화 기술과 결합할 수 없습니다.
+
+
+
+
+
+
+
+지원되는 아키텍처에서 퓨즈된 모듈을 활성화하려면, [`AwqConfig`] 를 생성하고 매개변수 `fuse_max_seq_len` 과 `do_fuse=True`를 설정해야 합니다. `fuse_max_seq_len` 매개변수는 전체 시퀀스 길이로, 컨텍스트 길이와 예상 생성 길이를 포함해야 합니다. 안전하게 사용하기 위해 더 큰 값으로 설정할 수 있습니다.
+
+예를 들어, [TheBloke/Mistral-7B-OpenOrca-AWQ](https://huggingface.co/TheBloke/Mistral-7B-OpenOrca-AWQ) 모델의 AWQ 모듈을 퓨즈해보겠습니다.
+
+```python
+import torch
+from transformers import AwqConfig, AutoModelForCausalLM
+
+model_id = "TheBloke/Mistral-7B-OpenOrca-AWQ"
+
+quantization_config = AwqConfig(
+ bits=4,
+ fuse_max_seq_len=512,
+ do_fuse=True,
+)
+
+model = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=quantization_config).to(0)
+```
+
+[TheBloke/Mistral-7B-OpenOrca-AWQ](https://huggingface.co/TheBloke/Mistral-7B-OpenOrca-AWQ) 모델은 퓨즈된 모듈이 있는 경우와 없는 경우 모두 `batch_size=1` 로 성능 평가되었습니다.
+
+퓨즈되지 않은 모듈
+
+| 배치 크기 | 프리필 길이 | 디코드 길이 | 프리필 토큰/초 | 디코드 토큰/초 | 메모리 (VRAM) |
+|-------------:|-----------------:|----------------:|-------------------:|------------------:|:----------------|
+| 1 | 32 | 32 | 60.0984 | 38.4537 | 4.50 GB (5.68%) |
+| 1 | 64 | 64 | 1333.67 | 31.6604 | 4.50 GB (5.68%) |
+| 1 | 128 | 128 | 2434.06 | 31.6272 | 4.50 GB (5.68%) |
+| 1 | 256 | 256 | 3072.26 | 38.1731 | 4.50 GB (5.68%) |
+| 1 | 512 | 512 | 3184.74 | 31.6819 | 4.59 GB (5.80%) |
+| 1 | 1024 | 1024 | 3148.18 | 36.8031 | 4.81 GB (6.07%) |
+| 1 | 2048 | 2048 | 2927.33 | 35.2676 | 5.73 GB (7.23%) |
+
+퓨즈된 모듈
+
+| 배치 크기 | 프리필 길이 | 디코드 길이 | 프리필 토큰/초 | 디코드 토큰/초 | 메모리 (VRAM) |
+|-------------:|-----------------:|----------------:|-------------------:|------------------:|:----------------|
+| 1 | 32 | 32 | 81.4899 | 80.2569 | 4.00 GB (5.05%) |
+| 1 | 64 | 64 | 1756.1 | 106.26 | 4.00 GB (5.05%) |
+| 1 | 128 | 128 | 2479.32 | 105.631 | 4.00 GB (5.06%) |
+| 1 | 256 | 256 | 1813.6 | 85.7485 | 4.01 GB (5.06%) |
+| 1 | 512 | 512 | 2848.9 | 97.701 | 4.11 GB (5.19%) |
+| 1 | 1024 | 1024 | 3044.35 | 87.7323 | 4.41 GB (5.57%) |
+| 1 | 2048 | 2048 | 2715.11 | 89.4709 | 5.57 GB (7.04%) |
+
+퓨즈된 모듈 및 퓨즈되지 않은 모듈의 속도와 처리량은 [optimum-benchmark](https://github.com/huggingface/optimum-benchmark)라이브러리를 사용하여 테스트 되었습니다.
+
+
+
+
+ 포워드 피크 메모리 (forward peak memory)/배치 크기
+
+
+
+ 생성 처리량/배치크기
+
+
+
+
+
+
+퓨즈된 모듈을 지원하지 않는 아키텍처의 경우, `modules_to_fuse` 매개변수를 사용해 직접 퓨즈 매핑을 만들어 어떤 모듈을 퓨즈할지 정의해야합니다. 예로, [TheBloke/Yi-34B-AWQ](https://huggingface.co/TheBloke/Yi-34B-AWQ) 모델의 AWQ 모듈을 퓨즈하는 방법입니다.
+
+```python
+import torch
+from transformers import AwqConfig, AutoModelForCausalLM
+
+model_id = "TheBloke/Yi-34B-AWQ"
+
+quantization_config = AwqConfig(
+ bits=4,
+ fuse_max_seq_len=512,
+ modules_to_fuse={
+ "attention": ["q_proj", "k_proj", "v_proj", "o_proj"],
+ "layernorm": ["ln1", "ln2", "norm"],
+ "mlp": ["gate_proj", "up_proj", "down_proj"],
+ "use_alibi": False,
+ "num_attention_heads": 56,
+ "num_key_value_heads": 8,
+ "hidden_size": 7168
+ }
+)
+
+model = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=quantization_config).to(0)
+```
+
+ `modules_to_fuse` 매개변수는 다음을 포함해야 합니다:
+
+- `"attention"`: 어텐션 레이어는 다음 순서로 퓨즈하세요 : 쿼리 (query), 키 (key), 값 (value) , 출력 프로젝션 계층 (output projection layer). 해당 레이어를 퓨즈하지 않으려면 빈 리스트를 전달하세요.
+- `"layernorm"`: 사용자 정의 퓨즈 레이어 정규화로 교할 레이어 정규화 레이어명. 해당 레이어를 퓨즈하지 않으려면 빈 리스트를 전달하세요.
+- `"mlp"`: 단일 MLP 레이어로 퓨즈할 MLP 레이어 순서 : (게이트 (gate) (덴스(dense), 레이어(layer), 포스트 어텐션(post-attention)) / 위 / 아래 레이어).
+- `"use_alibi"`: 모델이 ALiBi positional embedding을 사용할 경우 설정합니다.
+- `"num_attention_heads"`: 어텐션 헤드 (attention heads)의 수를 설정합니다.
+- `"num_key_value_heads"`: 그룹화 쿼리 어텐션 (GQA)을 구현하는데 사용되는 키 값 헤드의 수를 설정합니다. `num_key_value_heads=num_attention_heads`로 설정할 경우, 모델은 다중 헤드 어텐션 (MHA)가 사용되며, `num_key_value_heads=1` 는 다중 쿼리 어텐션 (MQA)가, 나머지는 GQA가 사용됩니다.
+- `"hidden_size"`: 숨겨진 표현(hidden representations)의 차원을 설정합니다.
+
+
+
+
+
+
+## ExLlama-v2 서포트 [[exllama-v2-support]]
+
+최신 버전 `autoawq`는 빠른 프리필과 디코딩을 위해 ExLlama-v2 커널을 지원합니다. 시작하기 위해 먼저 최신 버전 `autoawq` 를 설치하세요 :
+
+```bash
+pip install git+https://github.com/casper-hansen/AutoAWQ.git
+```
+
+매개변수를 `version="exllama"`로 설정해 `AwqConfig()`를 생성하고 모델에 넘겨주세요.
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, AwqConfig
+
+quantization_config = AwqConfig(version="exllama")
+
+model = AutoModelForCausalLM.from_pretrained(
+ "TheBloke/Mistral-7B-Instruct-v0.1-AWQ",
+ quantization_config=quantization_config,
+ device_map="auto",
+)
+
+input_ids = torch.randint(0, 100, (1, 128), dtype=torch.long, device="cuda")
+output = model(input_ids)
+print(output.logits)
+
+tokenizer = AutoTokenizer.from_pretrained("TheBloke/Mistral-7B-Instruct-v0.1-AWQ")
+input_ids = tokenizer.encode("How to make a cake", return_tensors="pt").to(model.device)
+output = model.generate(input_ids, do_sample=True, max_length=50, pad_token_id=50256)
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+이 기능은 AMD GPUs에서 지원됩니다.
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/bitsandbytes.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/bitsandbytes.md
new file mode 100644
index 0000000000000000000000000000000000000000..f0420c2869ea13e104980c1847ac765909e0f1cd
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/bitsandbytes.md
@@ -0,0 +1,307 @@
+
+
+# bitsandbytes [[bitsandbytes]]
+
+[bitsandbytes](https://github.com/TimDettmers/bitsandbytes)는 모델을 8비트 및 4비트로 양자화하는 가장 쉬운 방법입니다. 8비트 양자화는 fp16의 이상치와 int8의 비이상치를 곱한 후, 비이상치 값을 fp16으로 다시 변환하고, 이들을 합산하여 fp16으로 가중치를 반환합니다. 이렇게 하면 이상치 값이 모델 성능에 미치는 저하 효과를 줄일 수 있습니다. 4비트 양자화는 모델을 더욱 압축하며, [QLoRA](https://hf.co/papers/2305.14314)와 함께 사용하여 양자화된 대규모 언어 모델을 미세 조정하는 데 흔히 사용됩니다.
+
+bitsandbytes를 사용하려면 다음 라이브러리가 설치되어 있어야 합니다:
+
+
+
+
+```bash
+pip install transformers accelerate bitsandbytes>0.37.0
+```
+
+
+
+
+```bash
+pip install bitsandbytes>=0.39.0
+pip install --upgrade accelerate transformers
+```
+
+
+
+
+이제 `BitsAndBytesConfig`를 [`~PreTrainedModel.from_pretrained`] 메소드에 전달하여 모델을 양자화할 수 있습니다. 이는 Accelerate 가져오기를 지원하고 `torch.nn.Linear` 레이어가 포함된 모든 모델에서 작동합니다.
+
+
+
+
+모델을 8비트로 양자화하면 메모리 사용량이 절반으로 줄어들며, 대규모 모델의 경우 사용 가능한 GPU를 효율적으로 활용하려면 `device_map="auto"`를 설정하세요.
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_8bit=True)
+
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ "bigscience/bloom-1b7",
+ quantization_config=quantization_config
+)
+```
+
+기본적으로 `torch.nn.LayerNorm`과 같은 다른 모듈은 `torch.float16`으로 변환됩니다. 원한다면 `torch_dtype` 매개변수로 이들 모듈의 데이터 유형을 변경할 수 있습니다:
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_8bit=True)
+
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ "facebook/opt-350m",
+ quantization_config=quantization_config,
+ torch_dtype=torch.float32
+)
+model_8bit.model.decoder.layers[-1].final_layer_norm.weight.dtype
+```
+
+모델이 8비트로 양자화되면 최신 버전의 Transformers와 bitsandbytes를 사용하지 않는 한 양자화된 가중치를 Hub에 푸시할 수 없습니다. 최신 버전을 사용하는 경우, [`~PreTrainedModel.push_to_hub`] 메소드를 사용하여 8비트 모델을 Hub에 푸시할 수 있습니다. 양자화 config.json 파일이 먼저 푸시되고, 그 다음 양자화된 모델 가중치가 푸시됩니다.
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_8bit=True)
+
+model = AutoModelForCausalLM.from_pretrained(
+ "bigscience/bloom-560m",
+ quantization_config=quantization_config
+)
+tokenizer = AutoTokenizer.from_pretrained("bigscience/bloom-560m")
+
+model.push_to_hub("bloom-560m-8bit")
+```
+
+
+
+
+모델을 4비트로 양자화하면 메모리 사용량이 4배 줄어들며, 대규모 모델의 경우 사용 가능한 GPU를 효율적으로 활용하려면 `device_map="auto"`를 설정하세요:
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_4bit=True)
+
+model_4bit = AutoModelForCausalLM.from_pretrained(
+ "bigscience/bloom-1b7",
+ quantization_config=quantization_config
+)
+```
+
+기본적으로 `torch.nn.LayerNorm`과 같은 다른 모듈은 `torch.float16`으로 변환됩니다. 원한다면 `torch_dtype` 매개변수로 이들 모듈의 데이터 유형을 변경할 수 있습니다:
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_4bit=True)
+
+model_4bit = AutoModelForCausalLM.from_pretrained(
+ "facebook/opt-350m",
+ quantization_config=quantization_config,
+ torch_dtype=torch.float32
+)
+model_4bit.model.decoder.layers[-1].final_layer_norm.weight.dtype
+```
+
+`bitsandbytes>=0.41.3`을 사용하는 경우 4비트 모델을 직렬화하고 Hugging Face Hub에 푸시할 수 있습니다. 모델을 4비트 정밀도로 가져온 후 `model.push_to_hub()`를 호출하면 됩니다. 또한 `model.save_pretrained()` 명령어로 로컬에 직렬화된 4비트 모델을 저장할 수도 있습니다.
+
+
+
+
+
+
+8비트 및 4비트 가중치로 훈련하는 것은 *추가* 매개변수에 대해서만 지원됩니다.
+
+
+
+메모리 사용량을 확인하려면 `get_memory_footprint`를 사용하세요:
+
+```py
+print(model.get_memory_footprint())
+```
+
+양자화된 모델은 [`~PreTrainedModel.from_pretrained`] 메소드를 사용하여 `load_in_8bit` 또는 `load_in_4bit` 매개변수를 지정하지 않고도 가져올 수 있습니다:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("{your_username}/bloom-560m-8bit", device_map="auto")
+```
+
+## 8비트 (LLM.int8() 알고리즘)[[8-bit-(llm.int8()-algorithm)]]
+
+
+
+8비트 양자화에 대한 자세한 내용을 알고 싶다면 이 [블로그 포스트](https://huggingface.co/blog/hf-bitsandbytes-integration)를 참조하세요!
+
+
+
+이 섹션에서는 오프로딩, 이상치 임곗값, 모듈 변환 건너뛰기 및 미세 조정과 같은 8비트 모델의 특정 기능을 살펴봅니다.
+
+### 오프로딩 [[offloading]]
+
+8비트 모델은 CPU와 GPU 간에 가중치를 오프로드하여 매우 큰 모델을 메모리에 장착할 수 있습니다. CPU로 전송된 가중치는 실제로 **float32**로 저장되며 8비트로 변환되지 않습니다. 예를 들어, [bigscience/bloom-1b7](https://huggingface.co/bigscience/bloom-1b7) 모델의 오프로드를 활성화하려면 [`BitsAndBytesConfig`]를 생성하는 것부터 시작하세요:
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(llm_int8_enable_fp32_cpu_offload=True)
+```
+
+CPU에 전달할 `lm_head`를 제외한 모든 것을 GPU에 적재할 수 있도록 사용자 정의 디바이스 맵을 설계합니다:
+
+```py
+device_map = {
+ "transformer.word_embeddings": 0,
+ "transformer.word_embeddings_layernorm": 0,
+ "lm_head": "cpu",
+ "transformer.h": 0,
+ "transformer.ln_f": 0,
+}
+```
+
+이제 사용자 정의 `device_map`과 `quantization_config`을 사용하여 모델을 가져옵니다:
+
+```py
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ "bigscience/bloom-1b7",
+ device_map=device_map,
+ quantization_config=quantization_config,
+)
+```
+
+### 이상치 임곗값[[outlier-threshold]]
+
+"이상치"는 특정 임곗값을 초과하는 은닉 상태 값을 의미하며, 이러한 값은 fp16으로 계산됩니다. 값은 일반적으로 정규 분포 ([-3.5, 3.5])를 따르지만, 대규모 모델의 경우 이 분포는 매우 다를 수 있습니다 ([-60, 6] 또는 [6, 60]). 8비트 양자화는 ~5 정도의 값에서 잘 작동하지만, 그 이상에서는 상당한 성능 저하가 발생합니다. 좋은 기본 임곗값 값은 6이지만, 더 불안정한 모델 (소형 모델 또는 미세 조정)에는 더 낮은 임곗값이 필요할 수 있습니다.
+
+모델에 가장 적합한 임곗값을 찾으려면 [`BitsAndBytesConfig`]에서 `llm_int8_threshold` 매개변수를 실험해보는 것이 좋습니다:
+
+```py
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig
+
+model_id = "bigscience/bloom-1b7"
+
+quantization_config = BitsAndBytesConfig(
+ llm_int8_threshold=10,
+)
+
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ model_id,
+ device_map=device_map,
+ quantization_config=quantization_config,
+)
+```
+
+### 모듈 변환 건너뛰기[[skip-module-conversion]]
+
+[Jukebox](model_doc/jukebox)와 같은 일부 모델은 모든 모듈을 8비트로 양자화할 필요가 없으며, 이는 실제로 불안정성을 유발할 수 있습니다. Jukebox의 경우, [`BitsAndBytesConfig`]의 `llm_int8_skip_modules` 매개변수를 사용하여 여러 `lm_head` 모듈을 건너뛰어야 합니다:
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+model_id = "bigscience/bloom-1b7"
+
+quantization_config = BitsAndBytesConfig(
+ llm_int8_skip_modules=["lm_head"],
+)
+
+model_8bit = AutoModelForCausalLM.from_pretrained(
+ model_id,
+ device_map="auto",
+ quantization_config=quantization_config,
+)
+```
+
+### 미세 조정[[finetuning]]
+
+[PEFT](https://github.com/huggingface/peft) 라이브러리를 사용하면 [flan-t5-large](https://huggingface.co/google/flan-t5-large) 및 [facebook/opt-6.7b](https://huggingface.co/facebook/opt-6.7b)와 같은 대규모 모델을 8비트 양자화로 미세 조정할 수 있습니다. 훈련 시 `device_map` 매개변수를 전달할 필요가 없으며, 모델을 자동으로 GPU에 가져옵니다. 그러나 원하는 경우 `device_map` 매개변수로 장치 맵을 사용자 정의할 수 있습니다 (`device_map="auto"`는 추론에만 사용해야 합니다).
+
+## 4비트 (QLoRA 알고리즘)[[4-bit-(qlora-algorithm)]]
+
+
+
+이 [노트북](https://colab.research.google.com/drive/1ge2F1QSK8Q7h0hn3YKuBCOAS0bK8E0wf)에서 4비트 양자화를 시도해보고 자세한 내용은 이 [블로그 게시물](https://huggingface.co/blog/4bit-transformers-bitsandbytes)에서 확인하세요.
+
+
+
+이 섹션에서는 계산 데이터 유형 변경, Normal Float 4 (NF4) 데이터 유형 사용, 중첩 양자화 사용과 같은 4비트 모델의 특정 기능 일부를 탐구합니다.
+
+
+### 데이터 유형 계산[[compute-data-type]]
+
+계산 속도를 높이기 위해 [`BitsAndBytesConfig`]에서 `bnb_4bit_compute_dtype` 매개변수를 사용하여 데이터 유형을 float32(기본값)에서 bf16으로 변경할 수 있습니다:
+
+```py
+import torch
+from transformers import BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16)
+```
+
+### Normal Float 4 (NF4)[[normal-float-4-(nf4)]]
+
+NF4는 [QLoRA](https://hf.co/papers/2305.14314) 논문에서 소개된 4비트 데이터 유형으로, 정규 분포에서 초기화된 가중치에 적합합니다. 4비트 기반 모델을 훈련할 때 NF4를 사용해야 합니다. 이는 [`BitsAndBytesConfig`]에서 `bnb_4bit_quant_type` 매개변수로 설정할 수 있습니다:
+
+```py
+from transformers import BitsAndBytesConfig
+
+nf4_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+)
+
+model_nf4 = AutoModelForCausalLM.from_pretrained(model_id, quantization_config=nf4_config)
+```
+
+추론의 경우, `bnb_4bit_quant_type`은 성능에 큰 영향을 미치지 않습니다. 그러나 모델 가중치와 일관성을 유지하기 위해 `bnb_4bit_compute_dtype` 및 `torch_dtype` 값을 사용해야 합니다.
+
+### 중첩 양자화[[nested-quantization]]
+
+중첩 양자화는 추가적인 성능 손실 없이 추가적인 메모리를 절약할 수 있는 기술입니다. 이 기능은 이미 양자화된 가중치의 2차 양자화를 수행하여 매개변수당 추가로 0.4비트를 절약합니다. 예를 들어, 중첩 양자화를 통해 16GB NVIDIA T4 GPU에서 시퀀스 길이 1024, 배치 크기 1, 그레이디언트 누적 4단계를 사용하여 [Llama-13b](https://huggingface.co/meta-llama/Llama-2-13b) 모델을 미세 조정할 수 있습니다.
+
+```py
+from transformers import BitsAndBytesConfig
+
+double_quant_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_use_double_quant=True,
+)
+
+model_double_quant = AutoModelForCausalLM.from_pretrained("meta-llama/Llama-2-13b", quantization_config=double_quant_config)
+```
+
+## `bitsandbytes` 모델의 비양자화[[dequantizing-`bitsandbytes`-models]]
+양자화된 후에는 모델을 원래의 정밀도로 비양자화할 수 있지만, 이는 모델의 품질이 약간 저하될 수 있습니다. 비양자화된 모델에 맞출 수 있는 충분한 GPU RAM이 있는지 확인하세요.
+
+```python
+from transformers import AutoModelForCausalLM, BitsAndBytesConfig, AutoTokenizer
+
+model_id = "facebook/opt-125m"
+
+model = AutoModelForCausalLM.from_pretrained(model_id, BitsAndBytesConfig(load_in_4bit=True))
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+
+model.dequantize()
+
+text = tokenizer("Hello my name is", return_tensors="pt").to(0)
+
+out = model.generate(**text)
+print(tokenizer.decode(out[0]))
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/eetq.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/eetq.md
new file mode 100644
index 0000000000000000000000000000000000000000..ef4f4a2684b9f00dd0bd82e1bb75cdf3639ed550
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/eetq.md
@@ -0,0 +1,47 @@
+
+
+# EETQ [[eetq]]
+
+[EETQ](https://github.com/NetEase-FuXi/EETQ) 라이브러리는 NVIDIA GPU에 대해 int8 채널별(per-channel) 가중치 전용 양자화(weight-only quantization)을 지원합니다. 고성능 GEMM 및 GEMV 커널은 FasterTransformer 및 TensorRT-LLM에서 가져왔습니다. 교정(calibration) 데이터셋이 필요 없으며, 모델을 사전에 양자화할 필요도 없습니다. 또한, 채널별 양자화(per-channel quantization) 덕분에 정확도 저하가 미미합니다.
+
+[릴리스 페이지](https://github.com/NetEase-FuXi/EETQ/releases)에서 eetq를 설치했는지 확인하세요.
+```
+pip install --no-cache-dir https://github.com/NetEase-FuXi/EETQ/releases/download/v1.0.0/EETQ-1.0.0+cu121+torch2.1.2-cp310-cp310-linux_x86_64.whl
+```
+또는 소스 코드 https://github.com/NetEase-FuXi/EETQ 에서 설치할 수 있습니다. EETQ는 CUDA 기능이 8.9 이하이고 7.0 이상이어야 합니다.
+```
+git clone https://github.com/NetEase-FuXi/EETQ.git
+cd EETQ/
+git submodule update --init --recursive
+pip install .
+```
+
+비양자화 모델은 "from_pretrained"를 통해 양자화할 수 있습니다.
+```py
+from transformers import AutoModelForCausalLM, EetqConfig
+path = "/path/to/model".
+quantization_config = EetqConfig("int8")
+model = AutoModelForCausalLM.from_pretrained(path, device_map="auto", quantization_config=quantization_config)
+```
+
+양자화된 모델은 "save_pretrained"를 통해 저장할 수 있으며, "from_pretrained"를 통해 다시 사용할 수 있습니다.
+
+```py
+quant_path = "/path/to/save/quantized/model"
+model.save_pretrained(quant_path)
+model = AutoModelForCausalLM.from_pretrained(quant_path, device_map="auto")
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/gptq.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/gptq.md
new file mode 100644
index 0000000000000000000000000000000000000000..c54f09c94a33036400b8992bab8fb34fb2a657c5
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/gptq.md
@@ -0,0 +1,120 @@
+
+
+# GPTQ [[gptq]]
+
+
+
+PEFT를 활용한 GPTQ 양자화를 사용해보시려면 이 [노트북](https://colab.research.google.com/drive/1_TIrmuKOFhuRRiTWN94iLKUFu6ZX4ceb)을 참고하시고, 자세한 내용은 이 [블로그 게시물](https://huggingface.co/blog/gptq-integration)에서 확인하세요!
+
+
+
+[AutoGPTQ](https://github.com/PanQiWei/AutoGPTQ) 라이브러리는 GPTQ 알고리즘을 구현합니다. 이는 훈련 후 양자화 기법으로, 가중치 행렬의 각 행을 독립적으로 양자화하여 오차를 최소화하는 가중치 버전을 찾습니다. 이 가중치는 int4로 양자화되지만, 추론 중에는 실시간으로 fp16으로 복원됩니다. 이는 int4 가중치가 GPU의 전역 메모리 대신 결합된 커널에서 역양자화되기 때문에 메모리 사용량을 4배 절약할 수 있으며, 더 낮은 비트 너비를 사용함으로써 통신 시간이 줄어들어 추론 속도가 빨라질 것으로 기대할 수 있습니다.
+
+시작하기 전에 다음 라이브러리들이 설치되어 있는지 확인하세요:
+
+```bash
+pip install auto-gptq
+pip install --upgrade accelerate optimum transformers
+```
+
+모델을 양자화하려면(현재 텍스트 모델만 지원됨) [`GPTQConfig`] 클래스를 생성하고 양자화할 비트 수, 양자화를 위한 가중치 교정 데이터셋, 그리고 데이터셋을 준비하기 위한 토크나이저를 설정해야 합니다.
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, GPTQConfig
+
+model_id = "facebook/opt-125m"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+gptq_config = GPTQConfig(bits=4, dataset="c4", tokenizer=tokenizer)
+```
+
+자신의 데이터셋을 문자열 리스트 형태로 전달할 수도 있지만, GPTQ 논문에서 사용한 동일한 데이터셋을 사용하는 것을 강력히 권장합니다.
+
+```py
+dataset = ["auto-gptq is an easy-to-use model quantization library with user-friendly apis, based on GPTQ algorithm."]
+gptq_config = GPTQConfig(bits=4, dataset=dataset, tokenizer=tokenizer)
+```
+
+양자화할 모델을 로드하고 `gptq_config`을 [`~AutoModelForCausalLM.from_pretrained`] 메소드에 전달하세요. 모델을 메모리에 맞추기 위해 `device_map="auto"`를 설정하여 모델을 자동으로 CPU로 오프로드하고, 양자화를 위해 모델 모듈이 CPU와 GPU 간에 이동할 수 있도록 합니다.
+
+```py
+quantized_model = AutoModelForCausalLM.from_pretrained(model_id, device_map="auto", quantization_config=gptq_config)
+```
+
+데이터셋이 너무 커서 메모리가 부족한 경우를 대비한 디스크 오프로드는 현재 지원하지 않고 있습니다. 이럴 때는 `max_memory` 매개변수를 사용하여 디바이스(GPU 및 CPU)에서 사용할 메모리 양을 할당해 보세요:
+
+```py
+quantized_model = AutoModelForCausalLM.from_pretrained(model_id, device_map="auto", max_memory={0: "30GiB", 1: "46GiB", "cpu": "30GiB"}, quantization_config=gptq_config)
+```
+
+
+
+하드웨어와 모델 매개변수량에 따라 모델을 처음부터 양자화하는 데 드는 시간이 서로 다를 수 있습니다. 예를 들어, 무료 등급의 Google Colab GPU로 비교적 가벼운 [facebook/opt-350m](https://huggingface.co/facebook/opt-350m) 모델을 양자화하는 데 약 5분이 걸리지만, NVIDIA A100으로 175B에 달하는 매개변수를 가진 모델을 양자화하는 데는 약 4시간에 달하는 시간이 걸릴 수 있습니다. 모델을 양자화하기 전에, Hub에서 해당 모델의 GPTQ 양자화 버전이 이미 존재하는지 확인하는 것이 좋습니다.
+
+
+
+모델이 양자화되면, 모델과 토크나이저를 Hub에 푸시하여 쉽게 공유하고 접근할 수 있습니다. [`GPTQConfig`]를 저장하기 위해 [`~PreTrainedModel.push_to_hub`] 메소드를 사용하세요:
+
+```py
+quantized_model.push_to_hub("opt-125m-gptq")
+tokenizer.push_to_hub("opt-125m-gptq")
+```
+
+양자화된 모델을 로컬에 저장하려면 [`~PreTrainedModel.save_pretrained`] 메소드를 사용할 수 있습니다. 모델이 `device_map` 매개변수로 양자화되었을 경우, 저장하기 전에 전체 모델을 GPU나 CPU로 이동해야 합니다. 예를 들어, 모델을 CPU에 저장하려면 다음과 같이 합니다:
+
+```py
+quantized_model.save_pretrained("opt-125m-gptq")
+tokenizer.save_pretrained("opt-125m-gptq")
+
+# device_map이 설정된 상태에서 양자화된 경우
+quantized_model.to("cpu")
+quantized_model.save_pretrained("opt-125m-gptq")
+```
+
+양자화된 모델을 다시 로드하려면 [`~PreTrainedModel.from_pretrained`] 메소드를 사용하고, `device_map="auto"`를 설정하여 모든 사용 가능한 GPU에 모델을 자동으로 분산시켜 더 많은 메모리를 사용하지 않으면서 모델을 더 빠르게 로드할 수 있습니다.
+
+```py
+from transformers import AutoModelForCausalLM
+
+model = AutoModelForCausalLM.from_pretrained("{your_username}/opt-125m-gptq", device_map="auto")
+```
+
+## ExLlama [[exllama]]
+
+[ExLlama](https://github.com/turboderp/exllama)은 [Llama](model_doc/llama) 모델의 Python/C++/CUDA 구현체로, 4비트 GPTQ 가중치를 사용하여 더 빠른 추론을 위해 설계되었습니다(이 [벤치마크](https://github.com/huggingface/optimum/tree/main/tests/benchmark#gptq-benchmark)를 참고하세요). ['GPTQConfig'] 객체를 생성할 때 ExLlama 커널이 기본적으로 활성화됩니다. 추론 속도를 더욱 높이기 위해, `exllama_config` 매개변수를 구성하여 [ExLlamaV2](https://github.com/turboderp/exllamav2) 커널을 사용할 수 있습니다:
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, GPTQConfig
+
+gptq_config = GPTQConfig(bits=4, exllama_config={"version":2})
+model = AutoModelForCausalLM.from_pretrained("{your_username}/opt-125m-gptq", device_map="auto", quantization_config=gptq_config)
+```
+
+
+
+4비트 모델만 지원되며, 양자화된 모델을 PEFT로 미세 조정하는 경우 ExLlama 커널을 비활성화할 것을 권장합니다.
+
+
+
+ExLlama 커널은 전체 모델이 GPU에 있을 때만 지원됩니다. AutoGPTQ(버전 0.4.2 이상)로 CPU에서 추론을 수행하는 경우 ExLlama 커널을 비활성화해야 합니다. 이를 위해 config.json 파일의 양자화 설정에서 ExLlama 커널과 관련된 속성을 덮어써야 합니다.
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, GPTQConfig
+gptq_config = GPTQConfig(bits=4, use_exllama=False)
+model = AutoModelForCausalLM.from_pretrained("{your_username}/opt-125m-gptq", device_map="cpu", quantization_config=gptq_config)
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/quanto.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/quanto.md
new file mode 100644
index 0000000000000000000000000000000000000000..7eff695051d6b8d14fed33672f337ace703d0c71
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quantization/quanto.md
@@ -0,0 +1,67 @@
+
+
+# Quanto[[quanto]]
+
+
+
+이 [노트북](https://colab.research.google.com/drive/16CXfVmtdQvciSh9BopZUDYcmXCDpvgrT?usp=sharing)으로 Quanto와 transformers를 사용해 보세요!
+
+
+
+
+[🤗 Quanto](https://github.com/huggingface/optimum-quanto) 라이브러리는 다목적 파이토치 양자화 툴킷입니다. 이 라이브러리에서 사용되는 양자화 방법은 선형 양자화입니다. Quanto는 다음과 같은 여러 가지 기능을 제공합니다:
+
+- 가중치 양자화 (`float8`,`int8`,`int4`,`int2`)
+- 활성화 양자화 (`float8`,`int8`)
+- 모달리티에 구애받지 않음 (e.g CV,LLM)
+- 장치에 구애받지 않음 (e.g CUDA,MPS,CPU)
+- `torch.compile` 호환성
+- 특정 장치에 대한 사용자 정의 커널의 쉬운 추가
+- QAT(양자화를 고려한 학습) 지원
+
+
+시작하기 전에 다음 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install quanto accelerate transformers
+```
+
+이제 [`~PreTrainedModel.from_pretrained`] 메소드에 [`QuantoConfig`] 객체를 전달하여 모델을 양자화할 수 있습니다. 이 방식은 `torch.nn.Linear` 레이어를 포함하는 모든 모달리티의 모든 모델에서 잘 작동합니다.
+
+허깅페이스의 transformers 라이브러리는 개발자 편의를 위해 quanto의 인터페이스를 일부 통합하여 지원하고 있으며, 이 방식으로는 가중치 양자화만 지원합니다. 활성화 양자화, 캘리브레이션, QAT 같은 더 복잡한 기능을 수행하기 위해서는 [quanto](https://github.com/huggingface/optimum-quanto) 라이브러리의 해당 함수를 직접 호출해야 합니다.
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer, QuantoConfig
+
+model_id = "facebook/opt-125m"
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+quantization_config = QuantoConfig(weights="int8")
+quantized_model = AutoModelForCausalLM.from_pretrained(model_id, device_map="cuda:0", quantization_config=quantization_config)
+```
+
+참고로, transformers에서는 아직 직렬화가 지원되지 않지만 곧 지원될 예정입니다!
+모델을 저장하고 싶으면 quanto 라이브러리를 대신 사용할 수 있습니다.
+
+Quanto 라이브러리는 양자화를 위해 선형 양자화 알고리즘을 사용합니다. 비록 기본적인 양자화 기술이지만, 좋은 결과를 얻는데 아주 큰 도움이 됩니다! 바로 아래에 있는 벤치마크(llama-2-7b의 펄플렉서티 지표)를 확인해 보세요. 더 많은 벤치마크는 [여기](https://github.com/huggingface/quanto/tree/main/bench/generation) 에서 찾을 수 있습니다.
+
+
+
+
+
+
+
+이 라이브러리는 대부분의 PTQ 최적화 알고리즘과 호환될 만큼 충분히 유연합니다. 앞으로의 계획은 가장 인기 있는 알고리즘(AWQ, Smoothquant)을 최대한 매끄럽게 통합하는 것입니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quicktour.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quicktour.md
new file mode 100644
index 0000000000000000000000000000000000000000..4c3b137aa00ff9d5221258a4e788ccdfd4841fd6
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/quicktour.md
@@ -0,0 +1,557 @@
+
+
+# 둘러보기 [[quick-tour]]
+
+[[open-in-colab]]
+
+🤗 Transformers를 시작해보세요! 개발해본 적이 없더라도 쉽게 읽을 수 있도록 쓰인 이 글은 [`pipeline`](./main_classes/pipelines)을 사용하여 추론하고, 사전학습된 모델과 전처리기를 [AutoClass](./model_doc/auto)로 로드하고, PyTorch 또는 TensorFlow로 모델을 빠르게 학습시키는 방법을 소개해 드릴 것입니다. 본 가이드에서 소개되는 개념을 (특히 초보자의 관점으로) 더 친절하게 접하고 싶다면, 튜토리얼이나 [코스](https://huggingface.co/course/chapter1/1)를 참조하기를 권장합니다.
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+!pip install transformers datasets evaluate accelerate
+```
+
+또한 선호하는 머신 러닝 프레임워크를 설치해야 합니다:
+
+
+
+
+```bash
+pip install torch
+```
+
+
+
+```bash
+pip install tensorflow
+```
+
+
+
+## 파이프라인 [[pipeline]]
+
+
+
+[`pipeline`](./main_classes/pipelines)은 사전 훈련된 모델로 추론하기에 가장 쉽고 빠른 방법입니다. [`pipeline`]은 여러 모달리티에서 다양한 과업을 쉽게 처리할 수 있으며, 아래 표에 표시된 몇 가지 과업을 기본적으로 지원합니다:
+
+
+
+사용 가능한 작업의 전체 목록은 [Pipelines API 참조](./main_classes/pipelines)를 확인하세요.
+
+
+
+| **태스크** | **설명** | **모달리티** | **파이프라인 ID** |
+|-----------------|----------------------------------------------------------------------|------------------|-----------------------------------------------|
+| 텍스트 분류 | 텍스트에 알맞은 레이블 붙이기 | 자연어 처리(NLP) | pipeline(task="sentiment-analysis") |
+| 텍스트 생성 | 주어진 문자열 입력과 이어지는 텍스트 생성하기 | 자연어 처리(NLP) | pipeline(task="text-generation") |
+| 개체명 인식 | 문자열의 각 토큰마다 알맞은 레이블 붙이기 (인물, 조직, 장소 등등) | 자연어 처리(NLP) | pipeline(task="ner") |
+| 질의응답 | 주어진 문맥과 질문에 따라 올바른 대답하기 | 자연어 처리(NLP) | pipeline(task="question-answering") |
+| 빈칸 채우기 | 문자열의 빈칸에 알맞은 토큰 맞추기 | 자연어 처리(NLP) | pipeline(task="fill-mask") |
+| 요약 | 텍스트나 문서를 요약하기 | 자연어 처리(NLP) | pipeline(task="summarization") |
+| 번역 | 텍스트를 한 언어에서 다른 언어로 번역하기 | 자연어 처리(NLP) | pipeline(task="translation") |
+| 이미지 분류 | 이미지에 알맞은 레이블 붙이기 | 컴퓨터 비전(CV) | pipeline(task="image-classification") |
+| 이미지 분할 | 이미지의 픽셀마다 레이블 붙이기(시맨틱, 파놉틱 및 인스턴스 분할 포함) | 컴퓨터 비전(CV) | pipeline(task="image-segmentation") |
+| 객체 탐지 | 이미지 속 객체의 경계 상자를 그리고 클래스를 예측하기 | 컴퓨터 비전(CV) | pipeline(task="object-detection") |
+| 오디오 분류 | 오디오 파일에 알맞은 레이블 붙이기 | 오디오 | pipeline(task="audio-classification") |
+| 자동 음성 인식 | 오디오 파일 속 음성을 텍스트로 바꾸기 | 오디오 | pipeline(task="automatic-speech-recognition") |
+| 시각 질의응답 | 주어진 이미지와 질문에 대해 올바르게 대답하기 | 멀티모달 | pipeline(task="vqa") |
+| 문서 질의응답 | 주어진 문서와 질문에 대해 올바르게 대답하기 | 멀티모달 | pipeline(task="document-question-answering") |
+| 이미지 캡션 달기 | 주어진 이미지의 캡션 생성하기 | 멀티모달 | pipeline(task="image-to-text") |
+
+먼저 [`pipeline`]의 인스턴스를 생성하고 사용할 작업을 지정합니다. 이 가이드에서는 감정 분석을 위해 [`pipeline`]을 사용하는 예제를 보여드리겠습니다:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("sentiment-analysis")
+```
+
+[`pipeline`]은 감정 분석을 위한 [사전 훈련된 모델](https://huggingface.co/distilbert/distilbert-base-uncased-finetuned-sst-2-english)과 토크나이저를 자동으로 다운로드하고 캐시합니다. 이제 `classifier`를 대상 텍스트에 사용할 수 있습니다:
+
+```py
+>>> classifier("We are very happy to show you the 🤗 Transformers library.")
+[{'label': 'POSITIVE', 'score': 0.9998}]
+```
+
+만약 입력이 여러 개 있는 경우, 입력을 리스트로 [`pipeline`]에 전달하여, 사전 훈련된 모델의 출력을 딕셔너리로 이루어진 리스트 형태로 받을 수 있습니다:
+
+```py
+>>> results = classifier(["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."])
+>>> for result in results:
+... print(f"label: {result['label']}, with score: {round(result['score'], 4)}")
+label: POSITIVE, with score: 0.9998
+label: NEGATIVE, with score: 0.5309
+```
+
+[`pipeline`]은 주어진 과업에 관계없이 데이터셋 전부를 순회할 수도 있습니다. 이 예제에서는 자동 음성 인식을 과업으로 선택해 보겠습니다:
+
+```py
+>>> import torch
+>>> from transformers import pipeline
+
+>>> speech_recognizer = pipeline("automatic-speech-recognition", model="facebook/wav2vec2-base-960h")
+```
+
+데이터셋을 로드할 차례입니다. (자세한 내용은 🤗 Datasets [시작하기](https://huggingface.co/docs/datasets/quickstart#audio)을 참조하세요) 여기에서는 [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) 데이터셋을 로드하겠습니다:
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train") # doctest: +IGNORE_RESULT
+```
+
+데이터셋의 샘플링 레이트가 기존 모델인 [`facebook/wav2vec2-base-960h`](https://huggingface.co/facebook/wav2vec2-base-960h)의 훈련 당시 샘플링 레이트와 일치하는지 확인해야 합니다:
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=speech_recognizer.feature_extractor.sampling_rate))
+```
+
+`"audio"` 열을 호출하면 자동으로 오디오 파일을 가져와서 리샘플링합니다. 첫 4개 샘플에서 원시 웨이브폼 배열을 추출하고 파이프라인에 리스트로 전달하세요:
+
+```py
+>>> result = speech_recognizer(dataset[:4]["audio"])
+>>> print([d["text"] for d in result])
+['I WOULD LIKE TO SET UP A JOINT ACCOUNT WITH MY PARTNER HOW DO I PROCEED WITH DOING THAT', "FONDERING HOW I'D SET UP A JOIN TO HELL T WITH MY WIFE AND WHERE THE AP MIGHT BE", "I I'D LIKE TOY SET UP A JOINT ACCOUNT WITH MY PARTNER I'M NOT SEEING THE OPTION TO DO IT ON THE APSO I CALLED IN TO GET SOME HELP CAN I JUST DO IT OVER THE PHONE WITH YOU AND GIVE YOU THE INFORMATION OR SHOULD I DO IT IN THE AP AN I'M MISSING SOMETHING UQUETTE HAD PREFERRED TO JUST DO IT OVER THE PHONE OF POSSIBLE THINGS", 'HOW DO I FURN A JOINA COUT']
+```
+
+음성이나 비전과 같이 입력이 큰 대규모 데이터셋의 경우, 모든 입력을 메모리에 로드하려면 리스트 대신 제너레이터 형태로 전달해야 합니다. 자세한 내용은 [Pipelines API 참조](./main_classes/pipelines)를 확인하세요.
+
+### 파이프라인에서 다른 모델과 토크나이저 사용하기 [[use-another-model-and-tokenizer-in-the-pipeline]]
+
+[`pipeline`]은 [Hub](https://huggingface.co/models)의 모든 모델을 사용할 수 있기 때문에, [`pipeline`]을 다른 용도에 맞게 쉽게 수정할 수 있습니다. 예를 들어, 프랑스어 텍스트를 처리할 수 있는 모델을 사용하기 위해선 Hub의 태그를 사용하여 적절한 모델을 필터링하면 됩니다. 필터링된 결과의 상위 항목으로는 프랑스어 텍스트에 사용할 수 있는 다국어 [BERT 모델](https://huggingface.co/nlptown/bert-base-multilingual-uncased-sentiment)이 반환됩니다:
+
+```py
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+```
+
+
+
+[`AutoModelForSequenceClassification`]과 [`AutoTokenizer`]를 사용하여 사전 훈련된 모델과 관련된 토크나이저를 로드하세요 (다음 섹션에서 [`AutoClass`]에 대해 더 자세히 알아보겠습니다):
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+[`TFAutoModelForSequenceClassification`]과 [`AutoTokenizer`]를 사용하여 사전 훈련된 모델과 관련된 토크나이저를 로드하세요 (다음 섹션에서 [`TFAutoClass`]에 대해 더 자세히 알아보겠습니다):
+
+```py
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+[`pipeline`]에서 모델과 토크나이저를 지정하면, 이제 `classifier`를 프랑스어 텍스트에 적용할 수 있습니다:
+
+```py
+>>> classifier = pipeline("sentiment-analysis", model=model, tokenizer=tokenizer)
+>>> classifier("Nous sommes très heureux de vous présenter la bibliothèque 🤗 Transformers.")
+[{'label': '5 stars', 'score': 0.7273}]
+```
+
+마땅한 모델을 찾을 수 없는 경우 데이터를 기반으로 사전 훈련된 모델을 미세조정해야 합니다. 미세조정 방법에 대한 자세한 내용은 [미세조정 튜토리얼](./training)을 참조하세요. 사전 훈련된 모델을 미세조정한 후에는 모델을 Hub의 커뮤니티와 공유하여 머신러닝 민주화에 기여해주세요! 🤗
+
+## AutoClass [[autoclass]]
+
+
+
+[`AutoModelForSequenceClassification`]과 [`AutoTokenizer`] 클래스는 위에서 다룬 [`pipeline`]의 기능을 구현하는 데 사용됩니다. [AutoClass](./model_doc/auto)는 사전 훈련된 모델의 아키텍처를 이름이나 경로에서 자동으로 가져오는 '바로가기'입니다. 과업에 적합한 `AutoClass`를 선택하고 해당 전처리 클래스를 선택하기만 하면 됩니다.
+
+이전 섹션의 예제로 돌아가서 [`pipeline`]의 결과를 `AutoClass`를 활용해 복제하는 방법을 살펴보겠습니다.
+
+### AutoTokenizer [[autotokenizer]]
+
+토크나이저는 텍스트를 모델의 입력으로 사용하기 위해 숫자 배열 형태로 전처리하는 역할을 담당합니다. 토큰화 과정에는 단어를 어디에서 끊을지, 어느 수준까지 나눌지와 같은 여러 규칙들이 있습니다 (토큰화에 대한 자세한 내용은 [토크나이저 요약](./tokenizer_summary)을 참조하세요). 가장 중요한 점은 모델이 사전 훈련된 모델과 동일한 토큰화 규칙을 사용하도록 동일한 모델 이름으로 토크나이저를 인스턴스화해야 한다는 것입니다.
+
+[`AutoTokenizer`]로 토크나이저를 로드하세요:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+텍스트를 토크나이저에 전달하세요:
+
+```py
+>>> encoding = tokenizer("We are very happy to show you the 🤗 Transformers library.")
+>>> print(encoding)
+{'input_ids': [101, 11312, 10320, 12495, 19308, 10114, 11391, 10855, 10103, 100, 58263, 13299, 119, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+토크나이저는 다음을 포함한 딕셔너리를 반환합니다:
+
+* [input_ids](./glossary#input-ids): 토큰의 숫자 표현.
+* [attention_mask](.glossary#attention-mask): 어떤 토큰에 주의를 기울여야 하는지를 나타냅니다.
+
+토크나이저는 입력을 리스트 형태로도 받을 수 있으며, 텍스트를 패딩하고 잘라내어 일정한 길이의 묶음을 반환할 수도 있습니다:
+
+
+
+
+```py
+>>> pt_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="pt",
+... )
+```
+
+
+
+```py
+>>> tf_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="tf",
+... )
+```
+
+
+
+
+
+[전처리](./preprocessing) 튜토리얼을 참조하시면 토큰화에 대한 자세한 설명과 함께 이미지, 오디오와 멀티모달 입력을 전처리하기 위한 [`AutoImageProcessor`]와 [`AutoFeatureExtractor`], [`AutoProcessor`]의 사용방법도 알 수 있습니다.
+
+
+
+### AutoModel [[automodel]]
+
+
+
+🤗 Transformers는 사전 훈련된 인스턴스를 간단하고 통합된 방법으로 로드할 수 있습니다. 즉, [`AutoTokenizer`]처럼 [`AutoModel`]을 로드할 수 있습니다. 유일한 차이점은 과업에 알맞은 [`AutoModel`]을 선택해야 한다는 점입니다. 텍스트 (또는 시퀀스) 분류의 경우 [`AutoModelForSequenceClassification`]을 로드해야 합니다:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+[`AutoModel`] 클래스에서 지원하는 과업에 대해서는 [과업 요약](./task_summary)을 참조하세요.
+
+
+
+이제 전처리된 입력 묶음을 직접 모델에 전달해야 합니다. 아래처럼 `**`를 앞에 붙여 딕셔너리를 풀어주면 됩니다:
+
+```py
+>>> pt_outputs = pt_model(**pt_batch)
+```
+
+모델의 최종 활성화 함수 출력은 `logits` 속성에 담겨있습니다. `logits`에 softmax 함수를 적용하여 확률을 얻을 수 있습니다:
+
+```py
+>>> from torch import nn
+
+>>> pt_predictions = nn.functional.softmax(pt_outputs.logits, dim=-1)
+>>> print(pt_predictions)
+tensor([[0.0021, 0.0018, 0.0115, 0.2121, 0.7725],
+ [0.2084, 0.1826, 0.1969, 0.1755, 0.2365]], grad_fn=)
+```
+
+
+🤗 Transformers는 사전 훈련된 인스턴스를 간단하고 통합된 방법으로 로드할 수 있습니다. 즉, [`AutoTokenizer`]처럼 [`TFAutoModel`]을 로드할 수 있습니다. 유일한 차이점은 과업에 알맞은 [`TFAutoModel`]을 선택해야 한다는 점입니다. 텍스트 (또는 시퀀스) 분류의 경우 [`TFAutoModelForSequenceClassification`]을 로드해야 합니다:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+[`AutoModel`] 클래스에서 지원하는 과업에 대해서는 [과업 요약](./task_summary)을 참조하세요.
+
+
+
+이제 전처리된 입력 묶음을 직접 모델에 전달해야 합니다. 아래처럼 그대로 텐서를 전달하면 됩니다:
+
+```py
+>>> tf_outputs = tf_model(tf_batch)
+```
+
+모델의 최종 활성화 함수 출력은 `logits` 속성에 담겨있습니다. `logits`에 softmax 함수를 적용하여 확률을 얻을 수 있습니다:
+
+```py
+>>> import tensorflow as tf
+
+>>> tf_predictions = tf.nn.softmax(tf_outputs.logits, axis=-1)
+>>> tf_predictions # doctest: +IGNORE_RESULT
+```
+
+
+
+
+
+모든 🤗 Transformers 모델(PyTorch 또는 TensorFlow)은 (softmax와 같은) 최종 활성화 함수 *이전에* 텐서를 출력합니다. 왜냐하면 최종 활성화 함수의 출력은 종종 손실 함수 출력과 결합되기 때문입니다. 모델 출력은 특수한 데이터 클래스이므로 IDE에서 자동 완성됩니다. 모델 출력은 튜플이나 딕셔너리처럼 동작하며 (정수, 슬라이스 또는 문자열로 인덱싱 가능), None인 속성은 무시됩니다.
+
+
+
+### 모델 저장하기 [[save-a-model]]
+
+
+
+미세조정된 모델을 토크나이저와 함께 저장하려면 [`PreTrainedModel.save_pretrained`]를 사용하세요:
+
+```py
+>>> pt_save_directory = "./pt_save_pretrained"
+>>> tokenizer.save_pretrained(pt_save_directory) # doctest: +IGNORE_RESULT
+>>> pt_model.save_pretrained(pt_save_directory)
+```
+
+모델을 다시 사용하려면 [`PreTrainedModel.from_pretrained`]로 모델을 다시 로드하세요:
+
+```py
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("./pt_save_pretrained")
+```
+
+
+미세조정된 모델을 토크나이저와 함께 저장하려면 [`TFPreTrainedModel.save_pretrained`]를 사용하세요:
+
+```py
+>>> tf_save_directory = "./tf_save_pretrained"
+>>> tokenizer.save_pretrained(tf_save_directory) # doctest: +IGNORE_RESULT
+>>> tf_model.save_pretrained(tf_save_directory)
+```
+
+모델을 다시 사용하려면 [`TFPreTrainedModel.from_pretrained`]로 모델을 다시 로드하세요:
+
+```py
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("./tf_save_pretrained")
+```
+
+
+
+🤗 Transformers의 멋진 기능 중 하나는 모델을 PyTorch 또는 TensorFlow 모델로 저장해뒀다가 다른 프레임워크로 다시 로드할 수 있는 점입니다. `from_pt` 또는 `from_tf` 매개변수를 사용하여 모델을 한 프레임워크에서 다른 프레임워크로 변환할 수 있습니다:
+
+
+
+
+```py
+>>> from transformers import AutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(pt_save_directory)
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(pt_save_directory, from_pt=True)
+```
+
+
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(tf_save_directory)
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(tf_save_directory, from_tf=True)
+```
+
+
+
+## 커스텀 모델 구축하기 [[custom-model-builds]]
+
+모델의 구성 클래스를 수정하여 모델의 구조를 바꿀 수 있습니다. (은닉층이나 어텐션 헤드의 수와 같은) 모델의 속성은 구성에서 지정되기 때문입니다. 커스텀 구성 클래스로 모델을 만들면 처음부터 시작해야 합니다. 모델 속성은 무작위로 초기화되므로 의미 있는 결과를 얻으려면 먼저 모델을 훈련시켜야 합니다.
+
+먼저 [`AutoConfig`]를 가져오고 수정하고 싶은 사전학습된 모델을 로드하세요. [`AutoConfig.from_pretrained`] 내부에서 (어텐션 헤드 수와 같이) 변경하려는 속성를 지정할 수 있습니다:
+
+```py
+>>> from transformers import AutoConfig
+
+>>> my_config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased", n_heads=12)
+```
+
+
+
+[`AutoModel.from_config`]를 사용하여 바꾼 구성대로 모델을 생성하세요:
+
+```py
+>>> from transformers import AutoModel
+
+>>> my_model = AutoModel.from_config(my_config)
+```
+
+
+[`TFAutoModel.from_config`]를 사용하여 바꾼 구성대로 모델을 생성하세요:
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> my_model = TFAutoModel.from_config(my_config)
+```
+
+
+
+커스텀 구성에 대한 자세한 내용은 [커스텀 아키텍처 만들기](./create_a_model) 가이드를 확인하세요.
+
+## Trainer - PyTorch에 최적화된 훈련 루프 [[trainer-a-pytorch-optimized-training-loop]]
+
+모든 모델은 [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module)이므로 일반적인 훈련 루프에서 사용할 수 있습니다. 직접 훈련 루프를 작성할 수도 있지만, 🤗 Transformers는 PyTorch를 위한 [`Trainer`] 클래스를 제공합니다. 이 클래스에는 기본 훈련 루프가 포함되어 있으며 분산 훈련, 혼합 정밀도 등과 같은 기능을 추가로 제공합니다.
+
+과업에 따라 다르지만 일반적으로 [`Trainer`]에 다음 매개변수를 전달합니다:
+
+1. [`PreTrainedModel`] 또는 [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module)로 시작합니다:
+
+ ```py
+ >>> from transformers import AutoModelForSequenceClassification
+
+ >>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. [`TrainingArguments`]는 학습률, 배치 크기, 훈련할 에포크 수와 같은 모델 하이퍼파라미터를 포함합니다. 훈련 인자를 지정하지 않으면 기본값이 사용됩니다:
+
+ ```py
+ >>> from transformers import TrainingArguments
+
+ >>> training_args = TrainingArguments(
+ ... output_dir="path/to/save/folder/",
+ ... learning_rate=2e-5,
+ ... per_device_train_batch_size=8,
+ ... per_device_eval_batch_size=8,
+ ... num_train_epochs=2,
+ ... )
+ ```
+
+3. 토크나이저, 이미지 프로세서, 특징 추출기(feature extractor) 또는 프로세서와 전처리 클래스를 로드하세요:
+
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+4. 데이터셋을 로드하세요:
+
+ ```py
+ >>> from datasets import load_dataset
+
+ >>> dataset = load_dataset("rotten_tomatoes") # doctest: +IGNORE_RESULT
+ ```
+
+5. 데이터셋을 토큰화하는 함수를 생성하세요:
+
+ ```py
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"])
+ ```
+
+ 그리고 [`~datasets.Dataset.map`]로 데이터셋 전체에 적용하세요:
+
+ ```py
+ >>> dataset = dataset.map(tokenize_dataset, batched=True)
+ ```
+
+6. [`DataCollatorWithPadding`]을 사용하여 데이터셋의 표본 묶음을 만드세요:
+
+ ```py
+ >>> from transformers import DataCollatorWithPadding
+
+ >>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+ ```
+
+이제 위의 모든 클래스를 [`Trainer`]로 모으세요:
+
+```py
+>>> from transformers import Trainer
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=dataset["train"],
+... eval_dataset=dataset["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... ) # doctest: +SKIP
+```
+
+준비가 되었으면 [`~Trainer.train`]을 호출하여 훈련을 시작하세요:
+
+```py
+>>> trainer.train() # doctest: +SKIP
+```
+
+
+
+번역이나 요약과 같이 시퀀스-시퀀스 모델을 사용하는 과업에는 [`Seq2SeqTrainer`] 및 [`Seq2SeqTrainingArguments`] 클래스를 사용하세요.
+
+
+
+[`Trainer`] 내의 메서드를 서브클래스화하여 훈련 루프를 바꿀 수도 있습니다. 이러면 손실 함수, 옵티마이저, 스케줄러와 같은 기능 또한 바꿀 수 있게 됩니다. 변경 가능한 메소드에 대해서는 [`Trainer`] 문서를 참고하세요.
+
+훈련 루프를 수정하는 다른 방법은 [Callbacks](./main_classes/callback)를 사용하는 것입니다. Callbacks로 다른 라이브러리와 통합하고, 훈련 루프를 체크하여 진행 상황을 보고받거나, 훈련을 조기에 중단할 수 있습니다. Callbacks은 훈련 루프 자체를 바꾸지는 않습니다. 손실 함수와 같은 것을 바꾸려면 [`Trainer`]를 서브클래스화해야 합니다.
+
+## TensorFlow로 훈련시키기 [[train-with-tensorflow]]
+
+모든 모델은 [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model)이므로 [Keras](https://keras.io/) API를 통해 TensorFlow에서 훈련시킬 수 있습니다. 🤗 Transformers는 데이터셋을 쉽게 `tf.data.Dataset` 형태로 쉽게 로드할 수 있는 [`~TFPreTrainedModel.prepare_tf_dataset`] 메소드를 제공하기 때문에, Keras의 [`compile`](https://keras.io/api/models/model_training_apis/#compile-method) 및 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) 메소드로 바로 훈련을 시작할 수 있습니다.
+
+1. [`TFPreTrainedModel`] 또는 [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model)로 시작합니다:
+
+ ```py
+ >>> from transformers import TFAutoModelForSequenceClassification
+
+ >>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. 토크나이저, 이미지 프로세서, 특징 추출기(feature extractor) 또는 프로세서와 같은 전처리 클래스를 로드하세요:
+
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+3. 데이터셋을 토큰화하는 함수를 생성하세요:
+
+ ```py
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"]) # doctest: +SKIP
+ ```
+
+4. [`~datasets.Dataset.map`]을 사용하여 전체 데이터셋에 토큰화 함수를 적용하고, 데이터셋과 토크나이저를 [`~TFPreTrainedModel.prepare_tf_dataset`]에 전달하세요. 배치 크기를 변경하거나 데이터셋을 섞을 수도 있습니다:
+
+ ```py
+ >>> dataset = dataset.map(tokenize_dataset) # doctest: +SKIP
+ >>> tf_dataset = model.prepare_tf_dataset(
+ ... dataset["train"], batch_size=16, shuffle=True, tokenizer=tokenizer
+ ... ) # doctest: +SKIP
+ ```
+
+5. 준비되었으면 `compile` 및 `fit`를 호출하여 훈련을 시작하세요. 🤗 Transformers의 모든 모델은 과업과 관련된 기본 손실 함수를 가지고 있으므로 명시적으로 지정하지 않아도 됩니다:
+
+ ```py
+ >>> from tensorflow.keras.optimizers import Adam
+
+ >>> model.compile(optimizer=Adam(3e-5)) # No loss argument!
+ >>> model.fit(tf_dataset) # doctest: +SKIP
+ ```
+
+## 다음 단계는 무엇인가요? [[whats-next]]
+
+🤗 Transformers 둘러보기를 모두 읽으셨다면, 가이드를 살펴보고 더 구체적인 것을 수행하는 방법을 알아보세요. 이를테면 커스텀 모델 구축하는 방법, 과업에 알맞게 모델을 미세조정하는 방법, 스크립트로 모델 훈련하는 방법 등이 있습니다. 🤗 Transformers 핵심 개념에 대해 더 알아보려면 커피 한 잔 들고 개념 가이드를 살펴보세요!
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/run_scripts.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/run_scripts.md
new file mode 100644
index 0000000000000000000000000000000000000000..715a949dde4280e7abca29cd55a7717c70df6088
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/run_scripts.md
@@ -0,0 +1,375 @@
+
+
+# 스크립트로 실행하기[[train-with-a-script]]
+
+🤗 Transformers 노트북과 함께 [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch), [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow), 또는 [JAX/Flax](https://github.com/huggingface/transformers/tree/main/examples/flax)를 사용해 특정 태스크에 대한 모델을 훈련하는 방법을 보여주는 예제 스크립트도 있습니다.
+
+또한 [연구 프로젝트](https://github.com/huggingface/transformers/tree/main/examples/research_projects) 및 [레거시 예제](https://github.com/huggingface/transformers/tree/main/examples/legacy)에서 대부분 커뮤니티에서 제공한 스크립트를 찾을 수 있습니다.
+이러한 스크립트는 적극적으로 유지 관리되지 않으며 최신 버전의 라이브러리와 호환되지 않을 가능성이 높은 특정 버전의 🤗 Transformers를 필요로 합니다.
+
+예제 스크립트가 모든 문제에서 바로 작동하는 것은 아니며, 해결하려는 문제에 맞게 스크립트를 변경해야 할 수도 있습니다.
+이를 위해 대부분의 스크립트에는 데이터 전처리 방법이 나와있어 필요에 따라 수정할 수 있습니다.
+
+예제 스크립트에 구현하고 싶은 기능이 있으면 pull request를 제출하기 전에 [포럼](https://discuss.huggingface.co/) 또는 [이슈](https://github.com/huggingface/transformers/issues)에서 논의해 주세요.
+버그 수정은 환영하지만 가독성을 희생하면서까지 더 많은 기능을 추가하는 pull request는 병합(merge)하지 않을 가능성이 높습니다.
+
+이 가이드에서는 [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization) 및 [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/summarization)에서 요약 훈련하는
+ 스크립트 예제를 실행하는 방법을 설명합니다.
+특별한 설명이 없는 한 모든 예제는 두 프레임워크 모두에서 작동할 것으로 예상됩니다.
+
+## 설정하기[[setup]]
+
+최신 버전의 예제 스크립트를 성공적으로 실행하려면 새 가상 환경에서 **소스로부터 🤗 Transformers를 설치**해야 합니다:
+
+```bash
+git clone https://github.com/huggingface/transformers
+cd transformers
+pip install .
+```
+
+이전 버전의 예제 스크립트를 보려면 아래 토글을 클릭하세요:
+
+
+ 이전 버전의 🤗 Transformers 예제
+
+
+
+그리고 다음과 같이 복제(clone)해온 🤗 Transformers 버전을 특정 버전(예: v3.5.1)으로 전환하세요:
+
+```bash
+git checkout tags/v3.5.1
+```
+
+올바른 라이브러리 버전을 설정한 후 원하는 예제 폴더로 이동하여 예제별로 라이브러리에 대한 요구 사항(requirements)을 설치합니다:
+
+```bash
+pip install -r requirements.txt
+```
+
+## 스크립트 실행하기[[run-a-script]]
+
+
+
+예제 스크립트는 🤗 [Datasets](https://huggingface.co/docs/datasets/) 라이브러리에서 데이터 세트를 다운로드하고 전처리합니다.
+그런 다음 스크립트는 요약 기능을 지원하는 아키텍처에서 [Trainer](https://huggingface.co/docs/transformers/main_classes/trainer)를 사용하여 데이터 세트를 미세 조정합니다.
+다음 예는 [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail) 데이터 세트에서 [T5-small](https://huggingface.co/google-t5/t5-small)을 미세 조정합니다.
+T5 모델은 훈련 방식에 따라 추가 `source_prefix` 인수가 필요하며, 이 프롬프트는 요약 작업임을 T5에 알려줍니다.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+예제 스크립트는 🤗 [Datasets](https://huggingface.co/docs/datasets/) 라이브러리에서 데이터 세트를 다운로드하고 전처리합니다.
+그런 다음 스크립트는 요약 기능을 지원하는 아키텍처에서 Keras를 사용하여 데이터 세트를 미세 조정합니다.
+다음 예는 [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail) 데이터 세트에서 [T5-small](https://huggingface.co/google-t5/t5-small)을 미세 조정합니다.
+T5 모델은 훈련 방식에 따라 추가 `source_prefix` 인수가 필요하며, 이 프롬프트는 요약 작업임을 T5에 알려줍니다.
+```bash
+python examples/tensorflow/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## 혼합 정밀도(mixed precision)로 분산 훈련하기[[distributed-training-and-mixed-precision]]
+
+[Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) 클래스는 분산 훈련과 혼합 정밀도(mixed precision)를 지원하므로 스크립트에서도 사용할 수 있습니다.
+이 두 가지 기능을 모두 활성화하려면 다음 두 가지를 설정해야 합니다:
+
+- `fp16` 인수를 추가해 혼합 정밀도(mixed precision)를 활성화합니다.
+- `nproc_per_node` 인수를 추가해 사용할 GPU 개수를 설정합니다.
+
+```bash
+torchrun \
+ --nproc_per_node 8 pytorch/summarization/run_summarization.py \
+ --fp16 \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+TensorFlow 스크립트는 분산 훈련을 위해 [`MirroredStrategy`](https://www.tensorflow.org/guide/distributed_training#mirroredstrategy)를 활용하며, 훈련 스크립트에 인수를 추가할 필요가 없습니다.
+다중 GPU 환경이라면, TensorFlow 스크립트는 기본적으로 여러 개의 GPU를 사용합니다.
+
+## TPU 위에서 스크립트 실행하기[[run-a-script-on-a-tpu]]
+
+
+
+Tensor Processing Units (TPUs)는 성능을 가속화하기 위해 특별히 설계되었습니다.
+PyTorch는 [XLA](https://www.tensorflow.org/xla) 딥러닝 컴파일러와 함께 TPU를 지원합니다(자세한 내용은 [여기](https://github.com/pytorch/xla/blob/master/README.md) 참조).
+TPU를 사용하려면 `xla_spawn.py` 스크립트를 실행하고 `num_cores` 인수를 사용하여 사용하려는 TPU 코어 수를 설정합니다.
+
+```bash
+python xla_spawn.py --num_cores 8 \
+ summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+Tensor Processing Units (TPUs)는 성능을 가속화하기 위해 특별히 설계되었습니다.
+TensorFlow 스크립트는 TPU를 훈련에 사용하기 위해 [`TPUStrategy`](https://www.tensorflow.org/guide/distributed_training#tpustrategy)를 활용합니다.
+TPU를 사용하려면 TPU 리소스의 이름을 `tpu` 인수에 전달합니다.
+
+```bash
+python run_summarization.py \
+ --tpu name_of_tpu_resource \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## 🤗 Accelerate로 스크립트 실행하기[[run-a-script-with-accelerate]]
+
+🤗 [Accelerate](https://huggingface.co/docs/accelerate)는 PyTorch 훈련 과정에 대한 완전한 가시성을 유지하면서 여러 유형의 설정(CPU 전용, 다중 GPU, TPU)에서 모델을 훈련할 수 있는 통합 방법을 제공하는 PyTorch 전용 라이브러리입니다.
+🤗 Accelerate가 설치되어 있는지 확인하세요:
+
+> 참고: Accelerate는 빠르게 개발 중이므로 스크립트를 실행하려면 accelerate를 설치해야 합니다.
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+`run_summarization.py` 스크립트 대신 `run_summarization_no_trainer.py` 스크립트를 사용해야 합니다.
+🤗 Accelerate 클래스가 지원되는 스크립트는 폴더에 `task_no_trainer.py` 파일이 있습니다.
+다음 명령을 실행하여 구성 파일을 생성하고 저장합니다:
+```bash
+accelerate config
+```
+
+설정을 테스트하여 올바르게 구성되었는지 확인합니다:
+
+```bash
+accelerate test
+```
+
+이제 훈련을 시작할 준비가 되었습니다:
+
+```bash
+accelerate launch run_summarization_no_trainer.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir ~/tmp/tst-summarization
+```
+
+## 사용자 정의 데이터 세트 사용하기[[use-a-custom-dataset]]
+
+요약 스크립트는 사용자 지정 데이터 세트가 CSV 또는 JSON 파일인 경우 지원합니다.
+사용자 지정 데이터 세트를 사용하는 경우에는 몇 가지 추가 인수를 지정해야 합니다:
+
+- `train_file`과 `validation_file`은 훈련 및 검증 파일의 경로를 지정합니다.
+- `text_column`은 요약할 입력 텍스트입니다.
+- `summary_column`은 출력할 대상 텍스트입니다.
+
+사용자 지정 데이터 세트를 사용하는 요약 스크립트는 다음과 같습니다:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --train_file path_to_csv_or_jsonlines_file \
+ --validation_file path_to_csv_or_jsonlines_file \
+ --text_column text_column_name \
+ --summary_column summary_column_name \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --overwrite_output_dir \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --predict_with_generate
+```
+
+## 스크립트 테스트하기[[test-a-script]]
+
+전체 데이터 세트를 대상으로 훈련을 완료하는데 꽤 오랜 시간이 걸리기 때문에, 작은 데이터 세트에서 모든 것이 예상대로 실행되는지 확인하는 것이 좋습니다.
+
+다음 인수를 사용하여 데이터 세트를 최대 샘플 수로 잘라냅니다:
+- `max_train_samples`
+- `max_eval_samples`
+- `max_predict_samples`
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --max_train_samples 50 \
+ --max_eval_samples 50 \
+ --max_predict_samples 50 \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+모든 예제 스크립트가 `max_predict_samples` 인수를 지원하지는 않습니다.
+스크립트가 이 인수를 지원하는지 확실하지 않은 경우 `-h` 인수를 추가하여 확인하세요:
+
+```bash
+examples/pytorch/summarization/run_summarization.py -h
+```
+
+## 체크포인트(checkpoint)에서 훈련 이어서 하기[[resume-training-from-checkpoint]]
+
+또 다른 유용한 옵션은 이전 체크포인트에서 훈련을 재개하는 것입니다.
+이렇게 하면 훈련이 중단되더라도 처음부터 다시 시작하지 않고 중단한 부분부터 다시 시작할 수 있습니다.
+체크포인트에서 훈련을 재개하는 방법에는 두 가지가 있습니다.
+
+첫 번째는 `output_dir previous_output_dir` 인수를 사용하여 `output_dir`에 저장된 최신 체크포인트부터 훈련을 재개하는 방법입니다.
+이 경우 `overwrite_output_dir`을 제거해야 합니다:
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --output_dir previous_output_dir \
+ --predict_with_generate
+```
+
+두 번째는 `resume_from_checkpoint path_to_specific_checkpoint` 인수를 사용하여 특정 체크포인트 폴더에서 훈련을 재개하는 방법입니다.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --resume_from_checkpoint path_to_specific_checkpoint \
+ --predict_with_generate
+```
+
+## 모델 공유하기[[share-your-model]]
+
+모든 스크립트는 최종 모델을 [Model Hub](https://huggingface.co/models)에 업로드할 수 있습니다.
+시작하기 전에 Hugging Face에 로그인했는지 확인하세요:
+```bash
+huggingface-cli login
+```
+
+그런 다음 스크립트에 `push_to_hub` 인수를 추가합니다.
+이 인수는 Hugging Face 사용자 이름과 `output_dir`에 지정된 폴더 이름으로 저장소를 생성합니다.
+
+저장소에 특정 이름을 지정하려면 `push_to_hub_model_id` 인수를 사용하여 추가합니다.
+저장소는 네임스페이스 아래에 자동으로 나열됩니다.
+다음 예는 특정 저장소 이름으로 모델을 업로드하는 방법입니다:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --push_to_hub \
+ --push_to_hub_model_id finetuned-t5-cnn_dailymail \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/sagemaker.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/sagemaker.md
new file mode 100644
index 0000000000000000000000000000000000000000..18aafc28a1612d3c59cc39d9aeefc628c1ef697d
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/sagemaker.md
@@ -0,0 +1,28 @@
+
+
+# Amazon SageMaker에서 학습 실행하기[[run-training-on-amazon-sagemaker]]
+
+문서가 [hf.co/docs/sagemaker](https://huggingface.co/docs/sagemaker)로 이동되었습니다. 이 페이지는 `transformers` 5.0 에서 삭제될 예정입니다.
+
+### 목차[[table-of-content]]
+
+- [Train Hugging Face models on Amazon SageMaker with the SageMaker Python SDK](https://huggingface.co/docs/sagemaker/train)
+- [Deploy Hugging Face models to Amazon SageMaker with the SageMaker Python SDK](https://huggingface.co/docs/sagemaker/inference)
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/serialization.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/serialization.md
new file mode 100644
index 0000000000000000000000000000000000000000..2e521e2b7b4af83b4a95df0c3e28f17f957ba411
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/serialization.md
@@ -0,0 +1,181 @@
+
+
+# ONNX로 내보내기 [[export-to-onnx]]
+
+🤗 Transformers 모델을 제품 환경에서 배포하기 위해서는 모델을 직렬화된 형식으로 내보내고 특정 런타임과 하드웨어에서 로드하고 실행할 수 있으면 유용합니다.
+
+🤗 Optimum은 Transformers의 확장으로, PyTorch 또는 TensorFlow에서 모델을 ONNX와 TFLite와 같은 직렬화된 형식으로 내보낼 수 있도록 하는 `exporters` 모듈을 통해 제공됩니다. 🤗 Optimum은 또한 성능 최적화 도구 세트를 제공하여 특정 하드웨어에서 모델을 훈련하고 실행할 때 최대 효율성을 달성할 수 있습니다.
+
+이 안내서는 🤗 Optimum을 사용하여 🤗 Transformers 모델을 ONNX로 내보내는 방법을 보여줍니다. TFLite로 모델을 내보내는 안내서는 [TFLite로 내보내기 페이지](tflite)를 참조하세요.
+
+## ONNX로 내보내기 [[export-to-onnx]]
+
+[ONNX (Open Neural Network eXchange)](http://onnx.ai)는 PyTorch와 TensorFlow를 포함한 다양한 프레임워크에서 심층 학습 모델을 나타내는 데 사용되는 공통 연산자 세트와 공통 파일 형식을 정의하는 오픈 표준입니다. 모델이 ONNX 형식으로 내보내지면 이러한 연산자를 사용하여 신경망을 통해 데이터가 흐르는 흐름을 나타내는 계산 그래프(일반적으로 _중간 표현_이라고 함)가 구성됩니다.
+
+표준화된 연산자와 데이터 유형을 가진 그래프를 노출함으로써, ONNX는 프레임워크 간에 쉽게 전환할 수 있습니다. 예를 들어, PyTorch에서 훈련된 모델을 ONNX 형식으로 내보내고 TensorFlow에서 가져올 수 있습니다(그 반대도 가능합니다).
+
+ONNX 형식으로 내보낸 모델은 다음과 같이 사용할 수 있습니다:
+- [그래프 최적화](https://huggingface.co/docs/optimum/onnxruntime/usage_guides/optimization) 및 [양자화](https://huggingface.co/docs/optimum/onnxruntime/usage_guides/quantization)와 같은 기법을 사용하여 추론을 위해 최적화됩니다.
+- ONNX Runtime을 통해 실행할 수 있습니다. [`ORTModelForXXX` 클래스들](https://huggingface.co/docs/optimum/onnxruntime/package_reference/modeling_ort)을 통해 동일한 `AutoModel` API를 따릅니다. 이 API는 🤗 Transformers에서 사용하는 것과 동일합니다.
+- [최적화된 추론 파이프라인](https://huggingface.co/docs/optimum/main/en/onnxruntime/usage_guides/pipelines)을 사용할 수 있습니다. 이는 🤗 Transformers의 [`pipeline`] 함수와 동일한 API를 가지고 있습니다.
+
+🤗 Optimum은 구성 객체를 활용하여 ONNX 내보내기를 지원합니다. 이러한 구성 객체는 여러 모델 아키텍처에 대해 미리 준비되어 있으며 다른 아키텍처에 쉽게 확장할 수 있도록 설계되었습니다.
+
+미리 준비된 구성 목록은 [🤗 Optimum 문서](https://huggingface.co/docs/optimum/exporters/onnx/overview)를 참조하세요.
+
+🤗 Transformers 모델을 ONNX로 내보내는 두 가지 방법이 있습니다. 여기에서 두 가지 방법을 모두 보여줍니다:
+
+- 🤗 Optimum을 사용하여 CLI로 내보내기
+- `optimum.onnxruntime`을 사용하여 🤗 Optimum으로 ONNX로 내보내기
+
+### CLI를 사용하여 🤗 Transformers 모델을 ONNX로 내보내기 [[exporting-a-transformers-model-to-onnx-with-cli]]
+
+🤗 Transformers 모델을 ONNX로 내보내려면 먼저 추가 종속성을 설치하세요:
+
+```bash
+pip install optimum[exporters]
+```
+
+사용 가능한 모든 인수를 확인하려면 [🤗 Optimum 문서](https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/export_a_model#exporting-a-model-to-onnx-using-the-cli)를 참조하거나 명령줄에서 도움말을 보세요.
+
+```bash
+optimum-cli export onnx --help
+```
+
+예를 들어, 🤗 Hub에서 `distilbert/distilbert-base-uncased-distilled-squad`와 같은 모델의 체크포인트를 내보내려면 다음 명령을 실행하세요:
+
+```bash
+optimum-cli export onnx --model distilbert/distilbert-base-uncased-distilled-squad distilbert_base_uncased_squad_onnx/
+```
+
+위와 같이 진행 상황을 나타내는 로그가 표시되고 결과인 `model.onnx`가 저장된 위치가 표시됩니다.
+
+```bash
+Validating ONNX model distilbert_base_uncased_squad_onnx/model.onnx...
+ -[✓] ONNX model output names match reference model (start_logits, end_logits)
+ - Validating ONNX Model output "start_logits":
+ -[✓] (2, 16) matches (2, 16)
+ -[✓] all values close (atol: 0.0001)
+ - Validating ONNX Model output "end_logits":
+ -[✓] (2, 16) matches (2, 16)
+ -[✓] all values close (atol: 0.0001)
+The ONNX export succeeded and the exported model was saved at: distilbert_base_uncased_squad_onnx
+```
+
+위의 예제는 🤗 Hub에서 체크포인트를 내보내는 것을 설명합니다. 로컬 모델을 내보낼 때에는 모델의 가중치와 토크나이저 파일을 동일한 디렉토리(`local_path`)에 저장했는지 확인하세요. CLI를 사용할 때에는 🤗 Hub의 체크포인트 이름 대신 `model` 인수에 `local_path`를 전달하고 `--task` 인수를 제공하세요. 지원되는 작업의 목록은 [🤗 Optimum 문서](https://huggingface.co/docs/optimum/exporters/task_manager)를 참조하세요. `task` 인수가 제공되지 않으면 작업에 특화된 헤드 없이 모델 아키텍처로 기본 설정됩니다.
+
+```bash
+optimum-cli export onnx --model local_path --task question-answering distilbert_base_uncased_squad_onnx/
+```
+
+그 결과로 생성된 `model.onnx` 파일은 ONNX 표준을 지원하는 많은 [가속기](https://onnx.ai/supported-tools.html#deployModel) 중 하나에서 실행할 수 있습니다. 예를 들어, [ONNX Runtime](https://onnxruntime.ai/)을 사용하여 모델을 로드하고 실행할 수 있습니다:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> from optimum.onnxruntime import ORTModelForQuestionAnswering
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert_base_uncased_squad_onnx")
+>>> model = ORTModelForQuestionAnswering.from_pretrained("distilbert_base_uncased_squad_onnx")
+>>> inputs = tokenizer("What am I using?", "Using DistilBERT with ONNX Runtime!", return_tensors="pt")
+>>> outputs = model(**inputs)
+```
+
+Hub의 TensorFlow 체크포인트에 대해서도 동일한 프로세스가 적용됩니다. 예를 들어, [Keras organization](https://huggingface.co/keras-io)에서 순수한 TensorFlow 체크포인트를 내보내는 방법은 다음과 같습니다:
+
+```bash
+optimum-cli export onnx --model keras-io/transformers-qa distilbert_base_cased_squad_onnx/
+```
+
+### `optimum.onnxruntime`을 사용하여 🤗 Transformers 모델을 ONNX로 내보내기 [[exporting-a-transformers-model-to-onnx-with-optimumonnxruntime]]
+
+CLI 대신에 `optimum.onnxruntime`을 사용하여 프로그래밍 방식으로 🤗 Transformers 모델을 ONNX로 내보낼 수도 있습니다. 다음과 같이 진행하세요:
+
+```python
+>>> from optimum.onnxruntime import ORTModelForSequenceClassification
+>>> from transformers import AutoTokenizer
+
+>>> model_checkpoint = "distilbert_base_uncased_squad"
+>>> save_directory = "onnx/"
+
+>>> # Load a model from transformers and export it to ONNX
+>>> ort_model = ORTModelForSequenceClassification.from_pretrained(model_checkpoint, export=True)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_checkpoint)
+
+>>> # Save the onnx model and tokenizer
+>>> ort_model.save_pretrained(save_directory)
+>>> tokenizer.save_pretrained(save_directory)
+```
+
+### 지원되지 않는 아키텍처의 모델 내보내기 [[exporting-a-model-for-an-unsupported-architecture]]
+
+현재 내보낼 수 없는 모델을 지원하기 위해 기여하려면, 먼저 [`optimum.exporters.onnx`](https://huggingface.co/docs/optimum/exporters/onnx/overview)에서 지원되는지 확인한 후 지원되지 않는 경우에는 [🤗 Optimum에 기여](https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/contribute)하세요.
+
+### `transformers.onnx`를 사용하여 모델 내보내기 [[exporting-a-model-with-transformersonnx]]
+
+
+
+`tranformers.onnx`는 더 이상 유지되지 않습니다. 위에서 설명한 대로 🤗 Optimum을 사용하여 모델을 내보내세요. 이 섹션은 향후 버전에서 제거될 예정입니다.
+
+
+
+🤗 Transformers 모델을 ONNX로 내보내려면 추가 종속성을 설치하세요:
+
+```bash
+pip install transformers[onnx]
+```
+
+`transformers.onnx` 패키지를 Python 모듈로 사용하여 준비된 구성을 사용하여 체크포인트를 내보냅니다:
+
+```bash
+python -m transformers.onnx --model=distilbert/distilbert-base-uncased onnx/
+```
+
+이렇게 하면 `--model` 인수에 정의된 체크포인트의 ONNX 그래프가 내보내집니다. 🤗 Hub에서 제공하는 체크포인트나 로컬에 저장된 체크포인트를 전달할 수 있습니다. 결과로 생성된 `model.onnx` 파일은 ONNX 표준을 지원하는 많은 가속기 중 하나에서 실행할 수 있습니다. 예를 들어, 다음과 같이 ONNX Runtime을 사용하여 모델을 로드하고 실행할 수 있습니다:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> from onnxruntime import InferenceSession
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> session = InferenceSession("onnx/model.onnx")
+>>> # ONNX Runtime expects NumPy arrays as input
+>>> inputs = tokenizer("Using DistilBERT with ONNX Runtime!", return_tensors="np")
+>>> outputs = session.run(output_names=["last_hidden_state"], input_feed=dict(inputs))
+```
+
+필요한 출력 이름(예: `["last_hidden_state"]`)은 각 모델의 ONNX 구성을 확인하여 얻을 수 있습니다. 예를 들어, DistilBERT의 경우 다음과 같습니다:
+
+```python
+>>> from transformers.models.distilbert import DistilBertConfig, DistilBertOnnxConfig
+
+>>> config = DistilBertConfig()
+>>> onnx_config = DistilBertOnnxConfig(config)
+>>> print(list(onnx_config.outputs.keys()))
+["last_hidden_state"]
+```
+
+Hub의 TensorFlow 체크포인트에 대해서도 동일한 프로세스가 적용됩니다. 예를 들어, 다음과 같이 순수한 TensorFlow 체크포인트를 내보냅니다:
+
+```bash
+python -m transformers.onnx --model=keras-io/transformers-qa onnx/
+```
+
+로컬에 저장된 모델을 내보내려면 모델의 가중치 파일과 토크나이저 파일을 동일한 디렉토리에 저장한 다음, transformers.onnx 패키지의 --model 인수를 원하는 디렉토리로 지정하여 ONNX로 내보냅니다:
+
+```bash
+python -m transformers.onnx --model=local-pt-checkpoint onnx/
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/task_summary.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/task_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..a0e60c60924b99989eb14bcc322297c8d3bcc5d6
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/task_summary.md
@@ -0,0 +1,341 @@
+
+
+# 🤗 Transformers로 할 수 있는 것[[what__transformers_can_do]]
+
+🤗 Transformers는 자연어처리(NLP), 컴퓨터 비전, 오디오 및 음성 처리 작업에 대한 사전훈련된 최첨단 모델 라이브러리입니다.
+이 라이브러리는 트랜스포머 모델뿐만 아니라 컴퓨터 비전 작업을 위한 현대적인 합성곱 신경망과 같은 트랜스포머가 아닌 모델도 포함하고 있습니다.
+
+스마트폰, 앱, 텔레비전과 같은 오늘날 가장 인기 있는 소비자 제품을 살펴보면, 딥러닝 기술이 그 뒤에 사용되고 있을 확률이 높습니다.
+스마트폰으로 촬영한 사진에서 배경 객체를 제거하고 싶다면 어떻게 할까요? 이는 파놉틱 세그멘테이션 작업의 예입니다(아직 이게 무엇인지 모른다면, 다음 섹션에서 설명하겠습니다!).
+
+이 페이지는 다양한 음성 및 오디오, 컴퓨터 비전, NLP 작업을 🤗 Transformers 라이브러리를 활용하여 다루는 간단한 예제를 3줄의 코드로 제공합니다.
+
+## 오디오[[audio]]
+
+
+음성 및 오디오 처리 작업은 다른 모달리티와 약간 다릅니다. 이는 주로 오디오가 연속적인 신호로 입력되기 때문입니다.
+텍스트와 달리 원본 오디오 파형(waveform)은 문장이 단어로 나눠지는 것처럼 깔끔하게 이산적인 묶음으로 나눌 수 없습니다.
+이를 극복하기 위해 원본 오디오 신호는 일정한 간격으로 샘플링됩니다. 해당 간격 내에서 더 많은 샘플을 취할 경우 샘플링률이 높아지며, 오디오는 원본 오디오 소스에 더 가까워집니다.
+
+과거의 접근 방식은 오디오에서 유용한 특징을 추출하기 위해 오디오를 전처리하는 것이었습니다.
+하지만 현재는 원본 오디오 파형을 특성 인코더에 직접 넣어서 오디오 표현(representation)을 추출하는 것이 더 일반적입니다.
+이렇게 하면 전처리 단계가 단순해지고 모델이 가장 중요한 특징을 학습할 수 있습니다.
+
+### 오디오 분류[[audio_classification]]
+
+
+오디오 분류는 오디오 데이터에 미리 정의된 클래스 집합의 레이블을 지정하는 작업입니다. 이는 많은 구체적인 응용 프로그램을 포함한 넓은 범주입니다.
+
+일부 예시는 다음과 같습니다:
+
+* 음향 장면 분류: 오디오에 장면 레이블("사무실", "해변", "경기장")을 지정합니다.
+* 음향 이벤트 감지: 오디오에 소리 이벤트 레이블("차 경적", "고래 울음소리", "유리 파손")을 지정합니다.
+* 태깅: 여러 가지 소리(새 지저귐, 회의에서의 화자 식별)가 포함된 오디오에 레이블을 지정합니다.
+* 음악 분류: 음악에 장르 레이블("메탈", "힙합", "컨트리")을 지정합니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="audio-classification", model="superb/hubert-base-superb-er")
+>>> preds = classifier("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.4532, 'label': 'hap'},
+ {'score': 0.3622, 'label': 'sad'},
+ {'score': 0.0943, 'label': 'neu'},
+ {'score': 0.0903, 'label': 'ang'}]
+```
+
+### 자동 음성 인식[[automatic_speech_recognition]]
+
+
+자동 음성 인식(ASR)은 음성을 텍스트로 변환하는 작업입니다.
+음성은 인간의 자연스러운 의사소통 형태이기 때문에 ASR은 가장 일반적인 오디오 작업 중 하나입니다.
+오늘날 ASR 시스템은 스피커, 전화 및 자동차와 같은 "스마트" 기술 제품에 내장되어 있습니다.
+우리는 가상 비서에게 음악 재생, 알림 설정 및 날씨 정보를 요청할 수 있습니다.
+
+하지만 트랜스포머 아키텍처가 해결하는 데 도움을 준 핵심 도전 과제 중 하나는 양이 데이터 양이 적은 언어(low-resource language)에 대한 것입니다. 대량의 음성 데이터로 사전 훈련한 후 데이터 양이 적은 언어에서 레이블이 지정된 음성 데이터 1시간만으로 모델을 미세 조정하면 이전의 100배 많은 레이블이 지정된 데이터로 훈련된 ASR 시스템보다 훨씬 더 높은 품질의 결과를 얻을 수 있습니다.
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline(task="automatic-speech-recognition", model="openai/whisper-small")
+>>> transcriber("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+{'text': ' I have a dream that one day this nation will rise up and live out the true meaning of its creed.'}
+```
+
+## 컴퓨터 비전[[computer_vision]]
+
+컴퓨터 비전 작업 중 가장 초기의 성공적인 작업 중 하나는 [합성곱 신경망(CNN)](glossary#convolution)을 사용하여 우편번호 숫자 이미지를 인식하는 것이었습니다. 이미지는 픽셀로 구성되어 있으며 각 픽셀은 숫자 값으로 표현됩니다. 이로써 이미지를 픽셀 값의 행렬로 나타내는 것이 쉬워집니다. 특정한 픽셀 값의 조합은 이미지의 색상을 의미합니다.
+
+컴퓨터 비전 작업은 일반적으로 다음 두 가지 방법으로 접근 가능합니다:
+
+1. 합성곱을 사용하여 이미지의 낮은 수준 특징에서 높은 수준의 추상적인 요소까지 계층적으로 학습합니다.
+
+2. 이미지를 패치로 나누고 트랜스포머를 사용하여 점진적으로 각 이미지 패치가 서로 어떠한 방식으로 연관되어 이미지를 형성하는지 학습합니다. `CNN`에서 선호하는 상향식 접근법과는 달리, 이 방식은 흐릿한 이미지로 초안을 그리고 점진적으로 선명한 이미지로 만들어가는 것과 유사합니다.
+
+### 이미지 분류[[image_classification]]
+
+
+이미지 분류는 한 개의 전체 이미지에 미리 정의된 클래스 집합의 레이블을 지정하는 작업입니다.
+
+대부분의 분류 작업과 마찬가지로, 이미지 분류에는 다양한 실용적인 용도가 있으며, 일부 예시는 다음과 같습니다:
+
+
+* 의료: 질병을 감지하거나 환자 건강을 모니터링하기 위해 의료 이미지에 레이블을 지정합니다.
+* 환경: 위성 이미지를 분류하여 산림 벌채를 감시하고 야생 지역 관리를 위한 정보를 제공하거나 산불을 감지합니다.
+* 농업: 작물 이미지를 분류하여 식물 건강을 확인하거나 위성 이미지를 분류하여 토지 이용 관찰에 사용합니다.
+* 생태학: 동물이나 식물 종 이미지를 분류하여 야생 동물 개체군을 조사하거나 멸종 위기에 처한 종을 추적합니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="image-classification")
+>>> preds = classifier(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> print(*preds, sep="\n")
+{'score': 0.4335, 'label': 'lynx, catamount'}
+{'score': 0.0348, 'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor'}
+{'score': 0.0324, 'label': 'snow leopard, ounce, Panthera uncia'}
+{'score': 0.0239, 'label': 'Egyptian cat'}
+{'score': 0.0229, 'label': 'tiger cat'}
+```
+
+### 객체 탐지[[object_detection]]
+
+
+이미지 분류와 달리 객체 탐지는 이미지 내에서 여러 객체를 식별하고 바운딩 박스로 정의된 객체의 위치를 파악합니다.
+
+객체 탐지의 몇 가지 응용 예시는 다음과 같습니다:
+
+* 자율 주행 차량: 다른 차량, 보행자 및 신호등과 같은 일상적인 교통 객체를 감지합니다.
+* 원격 감지: 재난 모니터링, 도시 계획 및 기상 예측 등을 수행합니다.
+* 결함 탐지: 건물의 균열이나 구조적 손상, 제조 결함 등을 탐지합니다.
+
+
+```py
+>>> from transformers import pipeline
+
+>>> detector = pipeline(task="object-detection")
+>>> preds = detector(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"], "box": pred["box"]} for pred in preds]
+>>> preds
+[{'score': 0.9865,
+ 'label': 'cat',
+ 'box': {'xmin': 178, 'ymin': 154, 'xmax': 882, 'ymax': 598}}]
+```
+
+### 이미지 분할[[image_segmentation]]
+
+
+이미지 분할은 픽셀 차원의 작업으로, 이미지 내의 모든 픽셀을 클래스에 할당합니다. 이는 객체 탐지와 다릅니다. 객체 탐지는 바운딩 박스를 사용하여 이미지 내의 객체를 레이블링하고 예측하는 반면, 분할은 더 세분화된 작업입니다. 분할은 픽셀 수준에서 객체를 감지할 수 있습니다.
+
+이미지 분할에는 여러 유형이 있습니다:
+
+* 인스턴스 분할: 개체의 클래스를 레이블링하는 것 외에도, 개체의 각 구분된 인스턴스에도 레이블을 지정합니다 ("개-1", "개-2" 등).
+* 파놉틱 분할: 의미적 분할과 인스턴스 분할의 조합입니다. 각 픽셀을 의미적 클래스로 레이블링하는 **동시에** 개체의 각각 구분된 인스턴스로도 레이블을 지정합니다.
+
+분할 작업은 자율 주행 차량에서 유용하며, 주변 환경의 픽셀 수준 지도를 생성하여 보행자와 다른 차량 주변에서 안전하게 탐색할 수 있습니다. 또한 의료 영상에서도 유용합니다. 분할 작업이 픽셀 수준에서 객체를 감지할 수 있기 때문에 비정상적인 세포나 장기의 특징을 식별하는 데 도움이 될 수 있습니다. 이미지 분할은 의류 가상 시착이나 카메라를 통해 실제 세계에 가상 개체를 덧씌워 증강 현실 경험을 만드는 등 전자 상거래 분야에서도 사용될 수 있습니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> segmenter = pipeline(task="image-segmentation")
+>>> preds = segmenter(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> print(*preds, sep="\n")
+{'score': 0.9879, 'label': 'LABEL_184'}
+{'score': 0.9973, 'label': 'snow'}
+{'score': 0.9972, 'label': 'cat'}
+```
+
+### 깊이 추정[[depth_estimation]]
+
+깊이 추정은 카메라로부터 이미지 내부의 각 픽셀의 거리를 예측합니다. 이 컴퓨터 비전 작업은 특히 장면 이해와 재구성에 중요합니다. 예를 들어, 자율 주행 차량은 보행자, 교통 표지판 및 다른 차량과 같은 객체와의 거리를 이해하여 장애물과 충돌을 피해야 합니다. 깊이 정보는 또한 2D 이미지에서 3D 표현을 구성하는 데 도움이 되며 생물학적 구조나 건물의 고품질 3D 표현을 생성하는 데 사용될 수 있습니다.
+
+깊이 추정에는 두 가지 접근 방식이 있습니다:
+
+* 스테레오: 약간 다른 각도에서 촬영된 동일한 이미지 두 장을 비교하여 깊이를 추정합니다.
+* 단안: 단일 이미지에서 깊이를 추정합니다.
+
+
+```py
+>>> from transformers import pipeline
+
+>>> depth_estimator = pipeline(task="depth-estimation")
+>>> preds = depth_estimator(
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+```
+
+## 자연어처리[[natural_language_processing]]
+
+텍스트는 인간이 의사 소통하는 자연스러운 방식 중 하나이기 때문에 자연어처리 역시 가장 일반적인 작업 유형 중 하나입니다. 모델이 인식하는 형식으로 텍스트를 변환하려면 토큰화해야 합니다. 이는 텍스트 시퀀스를 개별 단어 또는 하위 단어(토큰)로 분할한 다음 이러한 토큰을 숫자로 변환하는 것을 의미합니다. 결과적으로 텍스트 시퀀스를 숫자 시퀀스로 표현할 수 있으며, 숫자 시퀀스를 다양한 자연어처리 작업을 해결하기 위한 모델에 입력할 수 있습니다!
+
+### 텍스트 분류[[text_classification]]
+
+다른 모달리티에서의 분류 작업과 마찬가지로 텍스트 분류는 미리 정의된 클래스 집합에서 텍스트 시퀀스(문장 수준, 단락 또는 문서 등)에 레이블을 지정합니다. 텍스트 분류에는 다양한 실용적인 응용 사례가 있으며, 일부 예시는 다음과 같습니다:
+
+* 감성 분석: 텍스트를 `긍정` 또는 `부정`과 같은 어떤 극성에 따라 레이블링하여 정치, 금융, 마케팅과 같은 분야에서 의사 결정에 정보를 제공하고 지원할 수 있습니다.
+* 콘텐츠 분류: 텍스트를 주제에 따라 레이블링(날씨, 스포츠, 금융 등)하여 뉴스 및 소셜 미디어 피드에서 정보를 구성하고 필터링하는 데 도움이 될 수 있습니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="sentiment-analysis")
+>>> preds = classifier("Hugging Face is the best thing since sliced bread!")
+>>> preds = [{"score": round(pred["score"], 4), "label": pred["label"]} for pred in preds]
+>>> preds
+[{'score': 0.9991, 'label': 'POSITIVE'}]
+```
+
+### 토큰 분류[[token_classification]]
+
+모든 자연어처리 작업에서는 텍스트가 개별 단어나 하위 단어로 분리되어 전처리됩니다. 분리된 단어를 [토큰](/glossary#token)이라고 합니다. 토큰 분류는 각 토큰에 미리 정의된 클래스 집합의 레이블을 할당합니다.
+
+토큰 분류의 두 가지 일반적인 유형은 다음과 같습니다:
+
+* 개체명 인식 (NER): 토큰을 조직, 인물, 위치 또는 날짜와 같은 개체 범주에 따라 레이블링합니다. NER은 특히 유전체학적인 환경에서 유전자, 단백질 및 약물 이름에 레이블을 지정하는 데 널리 사용됩니다.
+* 품사 태깅 (POS): 명사, 동사, 형용사와 같은 품사에 따라 토큰에 레이블을 할당합니다. POS는 번역 시스템이 동일한 단어가 문법적으로 어떻게 다른지 이해하는 데 도움이 됩니다 (명사로 사용되는 "bank(은행)"과 동사로 사용되는 "bank(예금을 예치하다)"과 같은 경우).
+
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline(task="ner")
+>>> preds = classifier("Hugging Face is a French company based in New York City.")
+>>> preds = [
+... {
+... "entity": pred["entity"],
+... "score": round(pred["score"], 4),
+... "index": pred["index"],
+... "word": pred["word"],
+... "start": pred["start"],
+... "end": pred["end"],
+... }
+... for pred in preds
+... ]
+>>> print(*preds, sep="\n")
+{'entity': 'I-ORG', 'score': 0.9968, 'index': 1, 'word': 'Hu', 'start': 0, 'end': 2}
+{'entity': 'I-ORG', 'score': 0.9293, 'index': 2, 'word': '##gging', 'start': 2, 'end': 7}
+{'entity': 'I-ORG', 'score': 0.9763, 'index': 3, 'word': 'Face', 'start': 8, 'end': 12}
+{'entity': 'I-MISC', 'score': 0.9983, 'index': 6, 'word': 'French', 'start': 18, 'end': 24}
+{'entity': 'I-LOC', 'score': 0.999, 'index': 10, 'word': 'New', 'start': 42, 'end': 45}
+{'entity': 'I-LOC', 'score': 0.9987, 'index': 11, 'word': 'York', 'start': 46, 'end': 50}
+{'entity': 'I-LOC', 'score': 0.9992, 'index': 12, 'word': 'City', 'start': 51, 'end': 55}
+```
+
+### 질의응답[[question_answering]]
+
+질의응답은 또 하나의 토큰 차원의 작업으로, 문맥이 있을 때(개방형 도메인)와 문맥이 없을 때(폐쇄형 도메인) 질문에 대한 답변을 반환합니다. 이 작업은 가상 비서에게 식당이 영업 중인지와 같은 질문을 할 때마다 발생할 수 있습니다. 고객 지원 또는 기술 지원을 제공하거나 검색 엔진이 요청한 정보를 검색하는 데 도움을 줄 수 있습니다.
+
+질문 답변에는 일반적으로 두 가지 유형이 있습니다:
+
+* 추출형: 질문과 문맥이 주어졌을 때, 모델이 주어진 문맥의 일부에서 가져온 텍스트의 범위를 답변으로 합니다.
+* 생성형: 질문과 문맥이 주어졌을 때, 주어진 문맥을 통해 답변을 생성합니다. 이 접근 방식은 [`QuestionAnsweringPipeline`] 대신 [`Text2TextGenerationPipeline`]을 통해 처리됩니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> question_answerer = pipeline(task="question-answering")
+>>> preds = question_answerer(
+... question="What is the name of the repository?",
+... context="The name of the repository is huggingface/transformers",
+... )
+>>> print(
+... f"score: {round(preds['score'], 4)}, start: {preds['start']}, end: {preds['end']}, answer: {preds['answer']}"
+... )
+score: 0.9327, start: 30, end: 54, answer: huggingface/transformers
+```
+
+### 요약[[summarization]]
+
+요약은 원본 문서의 의미를 최대한 보존하면서 긴 문서를 짧은 문서로 만드는 작업입니다. 요약은 `sequence-to-sequence` 작업입니다. 입력보다 짧은 텍스트 시퀀스를 출력합니다. 요약 작업은 독자가 장문 문서들의 주요 포인트를 빠르게 이해하는 데 도움을 줄 수 있습니다. 입법안, 법률 및 금융 문서, 특허 및 과학 논문은 요약 작업이 독자의 시간을 절약하고 독서 보조 도구로 사용될 수 있는 몇 가지 예시입니다.
+
+질문 답변과 마찬가지로 요약에는 두 가지 유형이 있습니다:
+
+* 추출형: 원본 텍스트에서 가장 중요한 문장을 식별하고 추출합니다.
+* 생성형: 원본 텍스트에서 목표 요약을 생성합니다. 입력 문서에 없는 새로운 단어를 포함할 수도 있습니다. [`SummarizationPipeline`]은 생성형 접근 방식을 사용합니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> summarizer = pipeline(task="summarization")
+>>> summarizer(
+... "In this work, we presented the Transformer, the first sequence transduction model based entirely on attention, replacing the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention. For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers. On both WMT 2014 English-to-German and WMT 2014 English-to-French translation tasks, we achieve a new state of the art. In the former task our best model outperforms even all previously reported ensembles."
+... )
+[{'summary_text': ' The Transformer is the first sequence transduction model based entirely on attention . It replaces the recurrent layers most commonly used in encoder-decoder architectures with multi-headed self-attention . For translation tasks, the Transformer can be trained significantly faster than architectures based on recurrent or convolutional layers .'}]
+```
+
+### 번역[[translation]]
+
+번역은 한 언어로 된 텍스트 시퀀스를 다른 언어로 변환하는 작업입니다. 이는 서로 다른 배경을 가진 사람들이 서로 소통하는 데 도움을 주는 중요한 역할을 합니다. 더 넓은 대중에게 콘텐츠를 번역하여 전달하거나, 새로운 언어를 배우는 데 도움이 되는 학습 도구가 될 수도 있습니다. 요약과 마찬가지로, 번역은 `sequence-to-sequence` 작업입니다. 즉, 모델은 입력 시퀀스를 받아서 출력이 되는 목표 시퀀스를 반환합니다.
+
+초기의 번역 모델은 대부분 단일 언어로 이루어져 있었지만, 최근에는 많은 언어 쌍 간에 번역을 수행할 수 있는 다중 언어 모델에 대한 관심이 높아지고 있습니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> text = "translate English to French: Hugging Face is a community-based open-source platform for machine learning."
+>>> translator = pipeline(task="translation", model="google-t5/t5-small")
+>>> translator(text)
+[{'translation_text': "Hugging Face est une tribune communautaire de l'apprentissage des machines."}]
+```
+
+### 언어 모델링[[language_modeling]]
+
+언어 모델링은 텍스트 시퀀스에서 단어를 예측하는 작업입니다. 사전 훈련된 언어 모델은 많은 다른 하위 작업에 따라 미세 조정될 수 있기 때문에 매우 인기 있는 자연어처리 작업이 되었습니다. 최근에는 제로 샷(zero-shot) 또는 퓨 샷(few-shot) 학습이 가능한 대규모 언어 모델(Large Language Models, LLM)에 대한 많은 관심이 발생하고 있습니다. 이는 모델이 명시적으로 훈련되지 않은 작업도 해결할 수 있다는 것을 의미합니다! 언어 모델은 유창하고 설득력 있는 텍스트를 생성하는 데 사용될 수 있지만, 텍스트가 항상 정확하지는 않을 수 있으므로 주의가 필요합니다.
+
+언어 모델링에는 두 가지 유형이 있습니다:
+
+* 인과적 언어 모델링: 이 모델의 목적은 시퀀스에서 다음 토큰을 예측하는 것이며, 미래 토큰이 마스킹 됩니다.
+ ```py
+ >>> from transformers import pipeline
+
+ >>> prompt = "Hugging Face is a community-based open-source platform for machine learning."
+ >>> generator = pipeline(task="text-generation")
+ >>> generator(prompt) # doctest: +SKIP
+ ```
+
+* 마스킹된 언어 모델링: 이 모델의 목적은 시퀀스 내의 마스킹된 토큰을 예측하는 것이며, 시퀀스 내의 모든 토큰에 대한 접근이 제공됩니다.
+
+ ```py
+ >>> text = "Hugging Face is a community-based open-source for machine learning."
+ >>> fill_mask = pipeline(task="fill-mask")
+ >>> preds = fill_mask(text, top_k=1)
+ >>> preds = [
+ ... {
+ ... "score": round(pred["score"], 4),
+ ... "token": pred["token"],
+ ... "token_str": pred["token_str"],
+ ... "sequence": pred["sequence"],
+ ... }
+ ... for pred in preds
+ ... ]
+ >>> preds
+ [{'score': 0.2236,
+ 'token': 1761,
+ 'token_str': ' platform',
+ 'sequence': 'Hugging Face is a community-based open-source platform for machine learning.'}]
+ ```
+
+이 페이지를 통해 각 모달리티의 다양한 작업 유형과 각 작업의 실용적 중요성에 대해 추가적인 배경 정보를 얻으셨기를 바랍니다. 다음 [섹션](tasks_explained)에서는 🤗 Transformer가 이러한 작업을 해결하는 **방법**에 대해 알아보실 수 있습니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/asr.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/asr.md
new file mode 100644
index 0000000000000000000000000000000000000000..d1e4a5e1d919831fc18ebbc36b82a2fb8269dcbc
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/asr.md
@@ -0,0 +1,375 @@
+
+
+# 자동 음성 인식[[automatic-speech-recognition]]
+
+[[open-in-colab]]
+
+
+
+자동 음성 인식(Automatic Speech Recognition, ASR)은 음성 신호를 텍스트로 변환하여 음성 입력 시퀀스를 텍스트 출력에 매핑합니다.
+Siri와 Alexa와 같은 가상 어시스턴트는 ASR 모델을 사용하여 일상적으로 사용자를 돕고 있으며, 회의 중 라이브 캡션 및 메모 작성과 같은 유용한 사용자 친화적 응용 프로그램도 많이 있습니다.
+
+이 가이드에서 소개할 내용은 아래와 같습니다:
+
+1. [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) 데이터 세트에서 [Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base)를 미세 조정하여 오디오를 텍스트로 변환합니다.
+2. 미세 조정한 모델을 추론에 사용합니다.
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/automatic-speech-recognition)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate jiwer
+```
+
+Hugging Face 계정에 로그인하면 모델을 업로드하고 커뮤니티에 공유할 수 있습니다. 토큰을 입력하여 로그인하세요.
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## MInDS-14 데이터 세트 가져오기[[load-minds-14-dataset]]
+
+먼저, 🤗 Datasets 라이브러리에서 [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) 데이터 세트의 일부분을 가져오세요.
+이렇게 하면 전체 데이터 세트에 대한 훈련에 시간을 들이기 전에 모든 것이 작동하는지 실험하고 검증할 수 있습니다.
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> minds = load_dataset("PolyAI/minds14", name="en-US", split="train[:100]")
+```
+
+[`~Dataset.train_test_split`] 메소드를 사용하여 데이터 세트의 `train`을 훈련 세트와 테스트 세트로 나누세요:
+
+```py
+>>> minds = minds.train_test_split(test_size=0.2)
+```
+
+그리고 데이터 세트를 확인하세요:
+
+```py
+>>> minds
+DatasetDict({
+ train: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 16
+ })
+ test: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 4
+ })
+})
+```
+
+데이터 세트에는 `lang_id`와 `english_transcription`과 같은 유용한 정보가 많이 포함되어 있지만, 이 가이드에서는 `audio`와 `transcription`에 초점을 맞출 것입니다. 다른 열은 [`~datasets.Dataset.remove_columns`] 메소드를 사용하여 제거하세요:
+
+```py
+>>> minds = minds.remove_columns(["english_transcription", "intent_class", "lang_id"])
+```
+
+예시를 다시 한번 확인해보세요:
+
+```py
+>>> minds["train"][0]
+{'audio': {'array': array([-0.00024414, 0. , 0. , ..., 0.00024414,
+ 0.00024414, 0.00024414], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'sampling_rate': 8000},
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
+```
+
+두 개의 필드가 있습니다:
+
+- `audio`: 오디오 파일을 가져오고 리샘플링하기 위해 호출해야 하는 음성 신호의 1차원 `array(배열)`
+- `transcription`: 목표 텍스트
+
+## 전처리[[preprocess]]
+
+다음으로 오디오 신호를 처리하기 위한 Wav2Vec2 프로세서를 가져옵니다:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base")
+```
+
+MInDS-14 데이터 세트의 샘플링 레이트는 8000kHz이므로([데이터 세트 카드](https://huggingface.co/datasets/PolyAI/minds14)에서 확인), 사전 훈련된 Wav2Vec2 모델을 사용하려면 데이터 세트를 16000kHz로 리샘플링해야 합니다:
+
+```py
+>>> minds = minds.cast_column("audio", Audio(sampling_rate=16_000))
+>>> minds["train"][0]
+{'audio': {'array': array([-2.38064706e-04, -1.58618059e-04, -5.43987835e-06, ...,
+ 2.78103951e-04, 2.38446111e-04, 1.18740834e-04], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'sampling_rate': 16000},
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
+```
+
+위의 'transcription'에서 볼 수 있듯이 텍스트는 대문자와 소문자가 섞여 있습니다. Wav2Vec2 토크나이저는 대문자 문자에 대해서만 훈련되어 있으므로 텍스트가 토크나이저의 어휘와 일치하는지 확인해야 합니다:
+
+```py
+>>> def uppercase(example):
+... return {"transcription": example["transcription"].upper()}
+
+
+>>> minds = minds.map(uppercase)
+```
+
+이제 다음 작업을 수행할 전처리 함수를 만들어보겠습니다:
+
+1. `audio` 열을 호출하여 오디오 파일을 가져오고 리샘플링합니다.
+2. 오디오 파일에서 `input_values`를 추출하고 프로세서로 `transcription` 열을 토큰화합니다.
+
+```py
+>>> def prepare_dataset(batch):
+... audio = batch["audio"]
+... batch = processor(audio["array"], sampling_rate=audio["sampling_rate"], text=batch["transcription"])
+... batch["input_length"] = len(batch["input_values"][0])
+... return batch
+```
+
+전체 데이터 세트에 전처리 함수를 적용하려면 🤗 Datasets [`~datasets.Dataset.map`] 함수를 사용하세요. `num_proc` 매개변수를 사용하여 프로세스 수를 늘리면 `map`의 속도를 높일 수 있습니다. [`~datasets.Dataset.remove_columns`] 메소드를 사용하여 필요하지 않은 열을 제거하세요:
+
+```py
+>>> encoded_minds = minds.map(prepare_dataset, remove_columns=minds.column_names["train"], num_proc=4)
+```
+
+🤗 Transformers에는 자동 음성 인식용 데이터 콜레이터가 없으므로 예제 배치를 생성하려면 [`DataCollatorWithPadding`]을 조정해야 합니다. 이렇게 하면 데이터 콜레이터는 텍스트와 레이블을 배치에서 가장 긴 요소의 길이에 동적으로 패딩하여 길이를 균일하게 합니다. `tokenizer` 함수에서 `padding=True`를 설정하여 텍스트를 패딩할 수 있지만, 동적 패딩이 더 효율적입니다.
+
+다른 데이터 콜레이터와 달리 이 특정 데이터 콜레이터는 `input_values`와 `labels`에 대해 다른 패딩 방법을 적용해야 합니다.
+
+```py
+>>> import torch
+
+>>> from dataclasses import dataclass, field
+>>> from typing import Any, Dict, List, Optional, Union
+
+
+>>> @dataclass
+... class DataCollatorCTCWithPadding:
+... processor: AutoProcessor
+... padding: Union[bool, str] = "longest"
+
+... def __call__(self, features: List[Dict[str, Union[List[int], torch.Tensor]]]) -> Dict[str, torch.Tensor]:
+... # 입력과 레이블을 분할합니다
+... # 길이가 다르고, 각각 다른 패딩 방법을 사용해야 하기 때문입니다
+... input_features = [{"input_values": feature["input_values"][0]} for feature in features]
+... label_features = [{"input_ids": feature["labels"]} for feature in features]
+
+... batch = self.processor.pad(input_features, padding=self.padding, return_tensors="pt")
+
+... labels_batch = self.processor.pad(labels=label_features, padding=self.padding, return_tensors="pt")
+
+... # 패딩에 대해 손실을 적용하지 않도록 -100으로 대체합니다
+... labels = labels_batch["input_ids"].masked_fill(labels_batch.attention_mask.ne(1), -100)
+
+... batch["labels"] = labels
+
+... return batch
+```
+
+이제 `DataCollatorForCTCWithPadding`을 인스턴스화합니다:
+
+```py
+>>> data_collator = DataCollatorCTCWithPadding(processor=processor, padding="longest")
+```
+
+## 평가하기[[evaluate]]
+
+훈련 중에 평가 지표를 포함하면 모델의 성능을 평가하는 데 도움이 되는 경우가 많습니다. 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하면 평가 방법을 빠르게 불러올 수 있습니다.
+이 작업에서는 [단어 오류율(Word Error Rate, WER)](https://huggingface.co/spaces/evaluate-metric/wer) 평가 지표를 가져옵니다.
+(평가 지표를 불러오고 계산하는 방법은 🤗 Evaluate [둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하세요):
+
+```py
+>>> import evaluate
+
+>>> wer = evaluate.load("wer")
+```
+
+그런 다음 예측값과 레이블을 [`~evaluate.EvaluationModule.compute`]에 전달하여 WER을 계산하는 함수를 만듭니다:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(pred):
+... pred_logits = pred.predictions
+... pred_ids = np.argmax(pred_logits, axis=-1)
+
+... pred.label_ids[pred.label_ids == -100] = processor.tokenizer.pad_token_id
+
+... pred_str = processor.batch_decode(pred_ids)
+... label_str = processor.batch_decode(pred.label_ids, group_tokens=False)
+
+... wer = wer.compute(predictions=pred_str, references=label_str)
+
+... return {"wer": wer}
+```
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었으며, 훈련을 설정할 때 이 함수로 되돌아올 것입니다.
+
+## 훈련하기[[train]]
+
+
+
+
+
+[`Trainer`]로 모델을 미세 조정하는 것이 익숙하지 않다면, [여기](../training#train-with-pytorch-trainer)에서 기본 튜토리얼을 확인해보세요!
+
+
+
+이제 모델 훈련을 시작할 준비가 되었습니다! [`AutoModelForCTC`]로 Wav2Vec2를 가져오세요. `ctc_loss_reduction` 매개변수로 CTC 손실에 적용할 축소(reduction) 방법을 지정하세요. 기본값인 합계 대신 평균을 사용하는 것이 더 좋은 경우가 많습니다:
+
+```py
+>>> from transformers import AutoModelForCTC, TrainingArguments, Trainer
+
+>>> model = AutoModelForCTC.from_pretrained(
+... "facebook/wav2vec2-base",
+... ctc_loss_reduction="mean",
+... pad_token_id=processor.tokenizer.pad_token_id,
+... )
+```
+
+이제 세 단계만 남았습니다:
+
+1. [`TrainingArguments`]에서 훈련 하이퍼파라미터를 정의하세요. `output_dir`은 모델을 저장할 경로를 지정하는 유일한 필수 매개변수입니다. `push_to_hub=True`를 설정하여 모델을 Hub에 업로드 할 수 있습니다(모델을 업로드하려면 Hugging Face에 로그인해야 합니다). [`Trainer`]는 각 에폭마다 WER을 평가하고 훈련 체크포인트를 저장합니다.
+2. 모델, 데이터 세트, 토크나이저, 데이터 콜레이터, `compute_metrics` 함수와 함께 [`Trainer`]에 훈련 인수를 전달하세요.
+3. [`~Trainer.train`]을 호출하여 모델을 미세 조정하세요.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_asr_mind_model",
+... per_device_train_batch_size=8,
+... gradient_accumulation_steps=2,
+... learning_rate=1e-5,
+... warmup_steps=500,
+... max_steps=2000,
+... gradient_checkpointing=True,
+... fp16=True,
+... group_by_length=True,
+... eval_strategy="steps",
+... per_device_eval_batch_size=8,
+... save_steps=1000,
+... eval_steps=1000,
+... logging_steps=25,
+... load_best_model_at_end=True,
+... metric_for_best_model="wer",
+... greater_is_better=False,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=encoded_minds["train"],
+... eval_dataset=encoded_minds["test"],
+... processing_class=processor.feature_extractor,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면 모두가 모델을 사용할 수 있도록 [`~transformers.Trainer.push_to_hub`] 메소드를 사용하여 모델을 Hub에 공유하세요:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+자동 음성 인식을 위해 모델을 미세 조정하는 더 자세한 예제는 영어 자동 음성 인식을 위한 [블로그 포스트](https://huggingface.co/blog/fine-tune-wav2vec2-english)와 다국어 자동 음성 인식을 위한 [포스트](https://huggingface.co/blog/fine-tune-xlsr-wav2vec2)를 참조하세요.
+
+
+
+## 추론하기[[inference]]
+
+좋아요, 이제 모델을 미세 조정했으니 추론에 사용할 수 있습니다!
+
+추론에 사용할 오디오 파일을 가져오세요. 필요한 경우 오디오 파일의 샘플링 비율을 모델의 샘플링 레이트에 맞게 리샘플링하는 것을 잊지 마세요!
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", "en-US", split="train")
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+>>> sampling_rate = dataset.features["audio"].sampling_rate
+>>> audio_file = dataset[0]["audio"]["path"]
+```
+
+추론을 위해 미세 조정된 모델을 시험해보는 가장 간단한 방법은 [`pipeline`]을 사용하는 것입니다. 모델을 사용하여 자동 음성 인식을 위한 `pipeline`을 인스턴스화하고 오디오 파일을 전달하세요:
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline("automatic-speech-recognition", model="stevhliu/my_awesome_asr_minds_model")
+>>> transcriber(audio_file)
+{'text': 'I WOUD LIKE O SET UP JOINT ACOUNT WTH Y PARTNER'}
+```
+
+
+
+텍스트로 변환된 결과가 꽤 괜찮지만 더 좋을 수도 있습니다! 더 나은 결과를 얻으려면 더 많은 예제로 모델을 미세 조정하세요!
+
+
+
+`pipeline`의 결과를 수동으로 재현할 수도 있습니다:
+
+
+
+오디오 파일과 텍스트를 전처리하고 PyTorch 텐서로 `input`을 반환할 프로세서를 가져오세요:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("stevhliu/my_awesome_asr_mind_model")
+>>> inputs = processor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+```
+
+입력을 모델에 전달하고 로짓을 반환하세요:
+
+```py
+>>> from transformers import AutoModelForCTC
+
+>>> model = AutoModelForCTC.from_pretrained("stevhliu/my_awesome_asr_mind_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+가장 높은 확률의 `input_ids`를 예측하고, 프로세서를 사용하여 예측된 `input_ids`를 다시 텍스트로 디코딩하세요:
+
+```py
+>>> import torch
+
+>>> predicted_ids = torch.argmax(logits, dim=-1)
+>>> transcription = processor.batch_decode(predicted_ids)
+>>> transcription
+['I WOUL LIKE O SET UP JOINT ACOUNT WTH Y PARTNER']
+```
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/audio_classification.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/audio_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..2defa691edef75ffaefb7a66a3d8ebfc3a95ae5e
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/audio_classification.md
@@ -0,0 +1,324 @@
+
+
+# 오디오 분류[[audio_classification]]
+
+[[open-in-colab]]
+
+
+
+오디오 분류는 텍스트와 마찬가지로 입력 데이터에 클래스 레이블 출력을 할당합니다. 유일한 차이점은 텍스트 입력 대신 원시 오디오 파형이 있다는 것입니다. 오디오 분류의 실제 적용 분야에는 화자의 의도 파악, 언어 분류, 소리로 동물 종을 식별하는 것 등이 있습니다.
+
+이 문서에서 방법을 알아보겠습니다:
+
+1. [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) 데이터 세트를 [Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base)로 미세 조정하여 화자의 의도를 분류합니다.
+2. 추론에 미세 조정된 모델을 사용하세요.
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/audio-classification)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+모델을 업로드하고 커뮤니티와 공유할 수 있도록 허깅페이스 계정에 로그인하는 것이 좋습니다. 메시지가 표시되면 토큰을 입력하여 로그인합니다:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## MInDS-14 데이터셋 불러오기[[load_minds_14_dataset]]
+
+먼저 🤗 Datasets 라이브러리에서 MinDS-14 데이터 세트를 가져옵니다:
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> minds = load_dataset("PolyAI/minds14", name="en-US", split="train")
+```
+
+데이터 세트의 `train` 분할을 [`~datasets.Dataset.train_test_split`] 메소드를 사용하여 더 작은 훈련 및 테스트 집합으로 분할합니다. 이렇게 하면 전체 데이터 세트에 더 많은 시간을 소비하기 전에 모든 것이 작동하는지 실험하고 확인할 수 있습니다.
+
+```py
+>>> minds = minds.train_test_split(test_size=0.2)
+```
+
+이제 데이터 집합을 살펴볼게요:
+
+```py
+>>> minds
+DatasetDict({
+ train: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 450
+ })
+ test: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 113
+ })
+})
+```
+
+데이터 세트에는 `lang_id` 및 `english_transcription`과 같은 유용한 정보가 많이 포함되어 있지만 이 가이드에서는 `audio` 및 `intent_class`에 중점을 둘 것입니다. 다른 열은 [`~datasets.Dataset.remove_columns`] 메소드를 사용하여 제거합니다:
+
+```py
+>>> minds = minds.remove_columns(["path", "transcription", "english_transcription", "lang_id"])
+```
+
+예시를 살펴보겠습니다:
+
+```py
+>>> minds["train"][0]
+{'audio': {'array': array([ 0. , 0. , 0. , ..., -0.00048828,
+ -0.00024414, -0.00024414], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602b9a5fbb1e6d0fbce91f52.wav',
+ 'sampling_rate': 8000},
+ 'intent_class': 2}
+```
+
+두 개의 필드가 있습니다:
+
+- `audio`: 오디오 파일을 가져오고 리샘플링하기 위해 호출해야 하는 음성 신호의 1차원 `배열`입니다.
+- `intent_class`: 화자의 의도에 대한 클래스 ID를 나타냅니다.
+
+모델이 레이블 ID에서 레이블 이름을 쉽게 가져올 수 있도록 레이블 이름을 정수로 매핑하는 사전을 만들거나 그 반대로 매핑하는 사전을 만듭니다:
+
+```py
+>>> labels = minds["train"].features["intent_class"].names
+>>> label2id, id2label = dict(), dict()
+>>> for i, label in enumerate(labels):
+... label2id[label] = str(i)
+... id2label[str(i)] = label
+```
+
+이제 레이블 ID를 레이블 이름으로 변환할 수 있습니다:
+
+```py
+>>> id2label[str(2)]
+'app_error'
+```
+
+## 전처리[[preprocess]]
+
+다음 단계는 오디오 신호를 처리하기 위해 Wav2Vec2 특징 추출기를 가져오는 것입니다:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base")
+```
+
+MinDS-14 데이터 세트의 샘플링 속도는 8khz이므로(이 정보는 [데이터세트 카드](https://huggingface.co/datasets/PolyAI/minds14)에서 확인할 수 있습니다), 사전 훈련된 Wav2Vec2 모델을 사용하려면 데이터 세트를 16kHz로 리샘플링해야 합니다:
+
+```py
+>>> minds = minds.cast_column("audio", Audio(sampling_rate=16_000))
+>>> minds["train"][0]
+{'audio': {'array': array([ 2.2098757e-05, 4.6582241e-05, -2.2803260e-05, ...,
+ -2.8419291e-04, -2.3305941e-04, -1.1425107e-04], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602b9a5fbb1e6d0fbce91f52.wav',
+ 'sampling_rate': 16000},
+ 'intent_class': 2}
+```
+
+이제 전처리 함수를 만듭니다:
+
+1. 가져올 `오디오` 열을 호출하고 필요한 경우 오디오 파일을 리샘플링합니다.
+2. 오디오 파일의 샘플링 속도가 모델에 사전 훈련된 오디오 데이터의 샘플링 속도와 일치하는지 확인합니다. 이 정보는 Wav2Vec2 [모델 카드](https://huggingface.co/facebook/wav2vec2-base)에서 확인할 수 있습니다.
+3. 긴 입력이 잘리지 않고 일괄 처리되도록 최대 입력 길이를 설정합니다.
+
+```py
+>>> def preprocess_function(examples):
+... audio_arrays = [x["array"] for x in examples["audio"]]
+... inputs = feature_extractor(
+... audio_arrays, sampling_rate=feature_extractor.sampling_rate, max_length=16000, truncation=True
+... )
+... return inputs
+```
+
+전체 데이터 세트에 전처리 기능을 적용하려면 🤗 Datasets [`~datasets.Dataset.map`] 함수를 사용합니다. `batched=True`를 설정하여 데이터 집합의 여러 요소를 한 번에 처리하면 `map`의 속도를 높일 수 있습니다. 필요하지 않은 열을 제거하고 `intent_class`의 이름을 모델이 예상하는 이름인 `label`로 변경합니다:
+
+```py
+>>> encoded_minds = minds.map(preprocess_function, remove_columns="audio", batched=True)
+>>> encoded_minds = encoded_minds.rename_column("intent_class", "label")
+```
+
+## 평가하기[[evaluate]]
+
+훈련 중에 메트릭을 포함하면 모델의 성능을 평가하는 데 도움이 되는 경우가 많습니다. 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하여 평가 방법을 빠르게 가져올 수 있습니다. 이 작업에서는 [accuracy(정확도)](https://huggingface.co/spaces/evaluate-metric/accuracy) 메트릭을 가져옵니다(메트릭을 가져오고 계산하는 방법에 대한 자세한 내용은 🤗 Evalutate [빠른 둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour) 참조하세요):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+그런 다음 예측과 레이블을 [`~evaluate.EvaluationModule.compute`]에 전달하여 정확도를 계산하는 함수를 만듭니다:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions = np.argmax(eval_pred.predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=eval_pred.label_ids)
+```
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었으며, 트레이닝을 설정할 때 이 함수를 사용합니다.
+
+## 훈련[[train]]
+
+
+
+
+
+[`Trainer`]로 모델을 미세 조정하는 데 익숙하지 않다면 기본 튜토리얼 [여기](../training#train-with-pytorch-trainer)을 살펴보세요!
+
+
+
+이제 모델 훈련을 시작할 준비가 되었습니다! [`AutoModelForAudioClassification`]을 이용해서 Wav2Vec2를 불러옵니다. 예상되는 레이블 수와 레이블 매핑을 지정합니다:
+
+```py
+>>> from transformers import AutoModelForAudioClassification, TrainingArguments, Trainer
+
+>>> num_labels = len(id2label)
+>>> model = AutoModelForAudioClassification.from_pretrained(
+... "facebook/wav2vec2-base", num_labels=num_labels, label2id=label2id, id2label=id2label
+... )
+```
+
+이제 세 단계만 남았습니다:
+
+1. 훈련 하이퍼파라미터를 [`TrainingArguments`]에 정의합니다. 유일한 필수 매개변수는 모델을 저장할 위치를 지정하는 `output_dir`입니다. `push_to_hub = True`를 설정하여 이 모델을 허브로 푸시합니다(모델을 업로드하려면 허깅 페이스에 로그인해야 합니다). 각 에폭이 끝날 때마다 [`Trainer`]가 정확도를 평가하고 훈련 체크포인트를 저장합니다.
+2. 모델, 데이터 세트, 토크나이저, 데이터 콜레이터, `compute_metrics` 함수와 함께 훈련 인자를 [`Trainer`]에 전달합니다.
+3. [`~Trainer.train`]을 호출하여 모델을 미세 조정합니다.
+
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_mind_model",
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... learning_rate=3e-5,
+... per_device_train_batch_size=32,
+... gradient_accumulation_steps=4,
+... per_device_eval_batch_size=32,
+... num_train_epochs=10,
+... warmup_ratio=0.1,
+... logging_steps=10,
+... load_best_model_at_end=True,
+... metric_for_best_model="accuracy",
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=encoded_minds["train"],
+... eval_dataset=encoded_minds["test"],
+... processing_class=feature_extractor,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면 모든 사람이 모델을 사용할 수 있도록 [`~transformers.Trainer.push_to_hub`] 메소드를 사용하여 모델을 허브에 공유하세요:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+For a more in-depth example of how to finetune a model for audio classification, take a look at the corresponding [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/audio_classification.ipynb).
+
+
+
+## 추론[[inference]]
+
+이제 모델을 미세 조정했으니 추론에 사용할 수 있습니다!
+
+추론을 실행할 오디오 파일을 가져옵니다. 필요한 경우 오디오 파일의 샘플링 속도를 모델의 샘플링 속도와 일치하도록 리샘플링하는 것을 잊지 마세요!
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train")
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+>>> sampling_rate = dataset.features["audio"].sampling_rate
+>>> audio_file = dataset[0]["audio"]["path"]
+```
+
+추론을 위해 미세 조정한 모델을 시험해 보는 가장 간단한 방법은 [`pipeline`]에서 사용하는 것입니다. 모델을 사용하여 오디오 분류를 위한 `pipeline`을 인스턴스화하고 오디오 파일을 전달합니다:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("audio-classification", model="stevhliu/my_awesome_minds_model")
+>>> classifier(audio_file)
+[
+ {'score': 0.09766869246959686, 'label': 'cash_deposit'},
+ {'score': 0.07998877018690109, 'label': 'app_error'},
+ {'score': 0.0781070664525032, 'label': 'joint_account'},
+ {'score': 0.07667109370231628, 'label': 'pay_bill'},
+ {'score': 0.0755252093076706, 'label': 'balance'}
+]
+```
+
+원하는 경우 `pipeline`의 결과를 수동으로 복제할 수도 있습니다:
+
+
+
+특징 추출기를 가져와서 오디오 파일을 전처리하고 `입력`을 PyTorch 텐서로 반환합니다:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("stevhliu/my_awesome_minds_model")
+>>> inputs = feature_extractor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+```
+
+모델에 입력을 전달하고 로짓을 반환합니다:
+
+```py
+>>> from transformers import AutoModelForAudioClassification
+
+>>> model = AutoModelForAudioClassification.from_pretrained("stevhliu/my_awesome_minds_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+확률이 가장 높은 클래스를 가져온 다음 모델의 `id2label` 매핑을 사용하여 이를 레이블로 변환합니다:
+
+```py
+>>> import torch
+
+>>> predicted_class_ids = torch.argmax(logits).item()
+>>> predicted_label = model.config.id2label[predicted_class_ids]
+>>> predicted_label
+'cash_deposit'
+```
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/document_question_answering.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/document_question_answering.md
new file mode 100644
index 0000000000000000000000000000000000000000..6c2d04f4ee859836401cf1e5d9c37c12c77f5827
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/document_question_answering.md
@@ -0,0 +1,476 @@
+
+
+# 문서 질의 응답(Document Question Answering) [[document_question_answering]]
+
+[[open-in-colab]]
+
+문서 시각적 질의 응답(Document Visual Question Answering)이라고도 하는
+문서 질의 응답(Document Question Answering)은 문서 이미지에 대한 질문에 답변을 주는 태스크입니다.
+이 태스크를 지원하는 모델의 입력은 일반적으로 이미지와 질문의 조합이고, 출력은 자연어로 된 답변입니다. 이러한 모델은 텍스트, 단어의 위치(바운딩 박스), 이미지 등 다양한 모달리티를 활용합니다.
+
+이 가이드는 다음 내용을 설명합니다:
+
+- [DocVQA dataset](https://huggingface.co/datasets/nielsr/docvqa_1200_examples_donut)을 사용해 [LayoutLMv2](../model_doc/layoutlmv2) 미세 조정하기
+- 추론을 위해 미세 조정된 모델을 사용하기
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/image-to-text)를 확인하는 것이 좋습니다.
+
+
+
+LayoutLMv2는 토큰의 마지막 은닉층 위에 질의 응답 헤드를 추가해 답변의 시작 토큰과 끝 토큰의 위치를 예측함으로써 문서 질의 응답 태스크를 해결합니다. 즉, 문맥이 주어졌을 때 질문에 답하는 정보를 추출하는 추출형 질의 응답(Extractive question answering)으로 문제를 처리합니다.
+문맥은 OCR 엔진의 출력에서 가져오며, 여기서는 Google의 Tesseract를 사용합니다.
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요. LayoutLMv2는 detectron2, torchvision 및 테서랙트를 필요로 합니다.
+
+```bash
+pip install -q transformers datasets
+```
+
+```bash
+pip install 'git+https://github.com/facebookresearch/detectron2.git'
+pip install torchvision
+```
+
+```bash
+sudo apt install tesseract-ocr
+pip install -q pytesseract
+```
+
+필요한 라이브러리들을 모두 설치한 후 런타임을 다시 시작합니다.
+
+커뮤니티에 당신의 모델을 공유하는 것을 권장합니다. Hugging Face 계정에 로그인해서 모델을 🤗 Hub에 업로드하세요.
+프롬프트가 실행되면, 로그인을 위해 토큰을 입력하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+몇 가지 전역 변수를 정의해 보겠습니다.
+
+```py
+>>> model_checkpoint = "microsoft/layoutlmv2-base-uncased"
+>>> batch_size = 4
+```
+
+## 데이터 불러오기 [[load-the-data]]
+
+이 가이드에서는 🤗 Hub에서 찾을 수 있는 전처리된 DocVQA의 작은 샘플을 사용합니다.
+DocVQA의 전체 데이터 세트를 사용하고 싶다면, [DocVQA homepage](https://rrc.cvc.uab.es/?ch=17)에 가입 후 다운로드 할 수 있습니다. 전체 데이터 세트를 다운로드 했다면, 이 가이드를 계속 진행하기 위해 [🤗 dataset에 파일을 가져오는 방법](https://huggingface.co/docs/datasets/loading#local-and-remote-files)을 확인하세요.
+
+```py
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("nielsr/docvqa_1200_examples")
+>>> dataset
+DatasetDict({
+ train: Dataset({
+ features: ['id', 'image', 'query', 'answers', 'words', 'bounding_boxes', 'answer'],
+ num_rows: 1000
+ })
+ test: Dataset({
+ features: ['id', 'image', 'query', 'answers', 'words', 'bounding_boxes', 'answer'],
+ num_rows: 200
+ })
+})
+```
+
+보시다시피, 데이터 세트는 이미 훈련 세트와 테스트 세트로 나누어져 있습니다. 무작위로 예제를 살펴보면서 특성을 확인해보세요.
+
+```py
+>>> dataset["train"].features
+```
+
+각 필드가 나타내는 내용은 다음과 같습니다:
+* `id`: 예제의 id
+* `image`: 문서 이미지를 포함하는 PIL.Image.Image 객체
+* `query`: 질문 문자열 - 여러 언어의 자연어로 된 질문
+* `answers`: 사람이 주석을 단 정답 리스트
+* `words` and `bounding_boxes`: OCR의 결과값들이며 이 가이드에서는 사용하지 않을 예정
+* `answer`: 다른 모델과 일치하는 답변이며 이 가이드에서는 사용하지 않을 예정
+
+영어로 된 질문만 남기고 다른 모델에 대한 예측을 포함하는 `answer` 특성을 삭제하겠습니다.
+그리고 주석 작성자가 제공한 데이터 세트에서 첫 번째 답변을 가져옵니다. 또는 무작위로 샘플을 추출할 수도 있습니다.
+
+```py
+>>> updated_dataset = dataset.map(lambda example: {"question": example["query"]["en"]}, remove_columns=["query"])
+>>> updated_dataset = updated_dataset.map(
+... lambda example: {"answer": example["answers"][0]}, remove_columns=["answer", "answers"]
+... )
+```
+
+이 가이드에서 사용하는 LayoutLMv2 체크포인트는 `max_position_embeddings = 512`로 훈련되었습니다(이 정보는 [체크포인트의 `config.json` 파일](https://huggingface.co/microsoft/layoutlmv2-base-uncased/blob/main/config.json#L18)에서 확인할 수 있습니다).
+바로 예제를 잘라낼 수도 있지만, 긴 문서의 끝에 답변이 있어 잘리는 상황을 피하기 위해 여기서는 임베딩이 512보다 길어질 가능성이 있는 몇 가지 예제를 제거하겠습니다.
+데이터 세트에 있는 대부분의 문서가 긴 경우 슬라이딩 윈도우 방법을 사용할 수 있습니다 - 자세한 내용을 확인하고 싶으면 이 [노트북](https://github.com/huggingface/notebooks/blob/main/examples/question_answering.ipynb)을 확인하세요.
+
+```py
+>>> updated_dataset = updated_dataset.filter(lambda x: len(x["words"]) + len(x["question"].split()) < 512)
+```
+
+이 시점에서 이 데이터 세트의 OCR 특성도 제거해 보겠습니다. OCR 특성은 다른 모델을 미세 조정하기 위한 것으로, 이 가이드에서 사용하는 모델의 입력 요구 사항과 일치하지 않기 때문에 이 특성을 사용하기 위해서는 일부 처리가 필요합니다.
+대신, 원본 데이터에 [`LayoutLMv2Processor`]를 사용하여 OCR 및 토큰화를 모두 수행할 수 있습니다.
+이렇게 하면 모델이 요구하는 입력을 얻을 수 있습니다.
+이미지를 수동으로 처리하려면, [`LayoutLMv2` model documentation](../model_doc/layoutlmv2)에서 모델이 요구하는 입력 포맷을 확인해보세요.
+
+```py
+>>> updated_dataset = updated_dataset.remove_columns("words")
+>>> updated_dataset = updated_dataset.remove_columns("bounding_boxes")
+```
+
+마지막으로, 데이터 탐색을 완료하기 위해 이미지 예시를 살펴봅시다.
+
+```py
+>>> updated_dataset["train"][11]["image"]
+```
+
+
+
+
+
+## 데이터 전처리 [[preprocess-the-data]]
+
+
+문서 질의 응답 태스크는 멀티모달 태스크이며, 각 모달리티의 입력이 모델의 요구에 맞게 전처리 되었는지 확인해야 합니다.
+이미지 데이터를 처리할 수 있는 이미지 프로세서와 텍스트 데이터를 인코딩할 수 있는 토크나이저를 결합한 [`LayoutLMv2Processor`]를 가져오는 것부터 시작해 보겠습니다.
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+```
+
+### 문서 이미지 전처리 [[preprocessing-document-images]]
+
+먼저, 프로세서의 `image_processor`를 사용해 모델에 대한 문서 이미지를 준비해 보겠습니다.
+기본값으로, 이미지 프로세서는 이미지 크기를 224x224로 조정하고 색상 채널의 순서가 올바른지 확인한 후 단어와 정규화된 바운딩 박스를 얻기 위해 테서랙트를 사용해 OCR를 적용합니다.
+이 튜토리얼에서 우리가 필요한 것과 기본값은 완전히 동일합니다. 이미지 배치에 기본 이미지 처리를 적용하고 OCR의 결과를 변환하는 함수를 작성합니다.
+
+```py
+>>> image_processor = processor.image_processor
+
+
+>>> def get_ocr_words_and_boxes(examples):
+... images = [image.convert("RGB") for image in examples["image"]]
+... encoded_inputs = image_processor(images)
+
+... examples["image"] = encoded_inputs.pixel_values
+... examples["words"] = encoded_inputs.words
+... examples["boxes"] = encoded_inputs.boxes
+
+... return examples
+```
+
+이 전처리를 데이터 세트 전체에 빠르게 적용하려면 [`~datasets.Dataset.map`]를 사용하세요.
+
+```py
+>>> dataset_with_ocr = updated_dataset.map(get_ocr_words_and_boxes, batched=True, batch_size=2)
+```
+
+### 텍스트 데이터 전처리 [[preprocessing-text-data]]
+
+이미지에 OCR을 적용했으면 데이터 세트의 텍스트 부분을 모델에 맞게 인코딩해야 합니다.
+이 인코딩에는 이전 단계에서 가져온 단어와 박스를 토큰 수준의 `input_ids`, `attention_mask`, `token_type_ids` 및 `bbox`로 변환하는 작업이 포함됩니다.
+텍스트를 전처리하려면 프로세서의 `tokenizer`가 필요합니다.
+
+```py
+>>> tokenizer = processor.tokenizer
+```
+
+위에서 언급한 전처리 외에도 모델을 위해 레이블을 추가해야 합니다. 🤗 Transformers의 `xxxForQuestionAnswering` 모델의 경우, 레이블은 `start_positions`와 `end_positions`로 구성되며 어떤 토큰이 답변의 시작과 끝에 있는지를 나타냅니다.
+
+레이블 추가를 위해서, 먼저 더 큰 리스트(단어 리스트)에서 하위 리스트(단어로 분할된 답변)을 찾을 수 있는 헬퍼 함수를 정의합니다.
+
+이 함수는 `words_list`와 `answer_list`, 이렇게 두 리스트를 입력으로 받습니다.
+그런 다음 `words_list`를 반복하여 `words_list`의 현재 단어(words_list[i])가 `answer_list`의 첫 번째 단어(answer_list[0])와 같은지,
+현재 단어에서 시작해 `answer_list`와 같은 길이만큼의 `words_list`의 하위 리스트가 `answer_list`와 일치하는지 확인합니다.
+이 조건이 참이라면 일치하는 항목을 발견했음을 의미하며, 함수는 일치 항목, 시작 인덱스(idx) 및 종료 인덱스(idx + len(answer_list) - 1)를 기록합니다. 일치하는 항목이 두 개 이상 발견되면 함수는 첫 번째 항목만 반환합니다. 일치하는 항목이 없다면 함수는 (`None`, 0, 0)을 반환합니다.
+
+```py
+>>> def subfinder(words_list, answer_list):
+... matches = []
+... start_indices = []
+... end_indices = []
+... for idx, i in enumerate(range(len(words_list))):
+... if words_list[i] == answer_list[0] and words_list[i : i + len(answer_list)] == answer_list:
+... matches.append(answer_list)
+... start_indices.append(idx)
+... end_indices.append(idx + len(answer_list) - 1)
+... if matches:
+... return matches[0], start_indices[0], end_indices[0]
+... else:
+... return None, 0, 0
+```
+
+이 함수가 어떻게 정답의 위치를 찾는지 설명하기 위해 다음 예제에서 함수를 사용해 보겠습니다:
+
+```py
+>>> example = dataset_with_ocr["train"][1]
+>>> words = [word.lower() for word in example["words"]]
+>>> match, word_idx_start, word_idx_end = subfinder(words, example["answer"].lower().split())
+>>> print("Question: ", example["question"])
+>>> print("Words:", words)
+>>> print("Answer: ", example["answer"])
+>>> print("start_index", word_idx_start)
+>>> print("end_index", word_idx_end)
+Question: Who is in cc in this letter?
+Words: ['wie', 'baw', 'brown', '&', 'williamson', 'tobacco', 'corporation', 'research', '&', 'development', 'internal', 'correspondence', 'to:', 'r.', 'h.', 'honeycutt', 'ce:', 't.f.', 'riehl', 'from:', '.', 'c.j.', 'cook', 'date:', 'may', '8,', '1995', 'subject:', 'review', 'of', 'existing', 'brainstorming', 'ideas/483', 'the', 'major', 'function', 'of', 'the', 'product', 'innovation', 'graup', 'is', 'to', 'develop', 'marketable', 'nove!', 'products', 'that', 'would', 'be', 'profitable', 'to', 'manufacture', 'and', 'sell.', 'novel', 'is', 'defined', 'as:', 'of', 'a', 'new', 'kind,', 'or', 'different', 'from', 'anything', 'seen', 'or', 'known', 'before.', 'innovation', 'is', 'defined', 'as:', 'something', 'new', 'or', 'different', 'introduced;', 'act', 'of', 'innovating;', 'introduction', 'of', 'new', 'things', 'or', 'methods.', 'the', 'products', 'may', 'incorporate', 'the', 'latest', 'technologies,', 'materials', 'and', 'know-how', 'available', 'to', 'give', 'then', 'a', 'unique', 'taste', 'or', 'look.', 'the', 'first', 'task', 'of', 'the', 'product', 'innovation', 'group', 'was', 'to', 'assemble,', 'review', 'and', 'categorize', 'a', 'list', 'of', 'existing', 'brainstorming', 'ideas.', 'ideas', 'were', 'grouped', 'into', 'two', 'major', 'categories', 'labeled', 'appearance', 'and', 'taste/aroma.', 'these', 'categories', 'are', 'used', 'for', 'novel', 'products', 'that', 'may', 'differ', 'from', 'a', 'visual', 'and/or', 'taste/aroma', 'point', 'of', 'view', 'compared', 'to', 'canventional', 'cigarettes.', 'other', 'categories', 'include', 'a', 'combination', 'of', 'the', 'above,', 'filters,', 'packaging', 'and', 'brand', 'extensions.', 'appearance', 'this', 'category', 'is', 'used', 'for', 'novel', 'cigarette', 'constructions', 'that', 'yield', 'visually', 'different', 'products', 'with', 'minimal', 'changes', 'in', 'smoke', 'chemistry', 'two', 'cigarettes', 'in', 'cne.', 'emulti-plug', 'te', 'build', 'yaur', 'awn', 'cigarette.', 'eswitchable', 'menthol', 'or', 'non', 'menthol', 'cigarette.', '*cigarettes', 'with', 'interspaced', 'perforations', 'to', 'enable', 'smoker', 'to', 'separate', 'unburned', 'section', 'for', 'future', 'smoking.', '«short', 'cigarette,', 'tobacco', 'section', '30', 'mm.', '«extremely', 'fast', 'buming', 'cigarette.', '«novel', 'cigarette', 'constructions', 'that', 'permit', 'a', 'significant', 'reduction', 'iretobacco', 'weight', 'while', 'maintaining', 'smoking', 'mechanics', 'and', 'visual', 'characteristics.', 'higher', 'basis', 'weight', 'paper:', 'potential', 'reduction', 'in', 'tobacco', 'weight.', '«more', 'rigid', 'tobacco', 'column;', 'stiffing', 'agent', 'for', 'tobacco;', 'e.g.', 'starch', '*colored', 'tow', 'and', 'cigarette', 'papers;', 'seasonal', 'promotions,', 'e.g.', 'pastel', 'colored', 'cigarettes', 'for', 'easter', 'or', 'in', 'an', 'ebony', 'and', 'ivory', 'brand', 'containing', 'a', 'mixture', 'of', 'all', 'black', '(black', 'paper', 'and', 'tow)', 'and', 'ail', 'white', 'cigarettes.', '499150498']
+Answer: T.F. Riehl
+start_index 17
+end_index 18
+```
+
+한편, 위 예제가 인코딩되면 다음과 같이 표시됩니다:
+
+```py
+>>> encoding = tokenizer(example["question"], example["words"], example["boxes"])
+>>> tokenizer.decode(encoding["input_ids"])
+[CLS] who is in cc in this letter? [SEP] wie baw brown & williamson tobacco corporation research & development ...
+```
+
+이제 인코딩된 입력에서 정답의 위치를 찾아야 합니다.
+* `token_type_ids`는 어떤 토큰이 질문에 속하는지, 그리고 어떤 토큰이 문서의 단어에 포함되는지를 알려줍니다.
+* `tokenizer.cls_token_id` 입력의 시작 부분에 있는 특수 토큰을 찾는 데 도움을 줍니다.
+* `word_ids`는 원본 `words`에서 찾은 답변을 전체 인코딩된 입력의 동일한 답과 일치시키고 인코딩된 입력에서 답변의 시작/끝 위치를 결정합니다.
+
+위 내용들을 염두에 두고 데이터 세트 예제의 배치를 인코딩하는 함수를 만들어 보겠습니다:
+
+```py
+>>> def encode_dataset(examples, max_length=512):
+... questions = examples["question"]
+... words = examples["words"]
+... boxes = examples["boxes"]
+... answers = examples["answer"]
+
+... # 예제 배치를 인코딩하고 start_positions와 end_positions를 초기화합니다
+... encoding = tokenizer(questions, words, boxes, max_length=max_length, padding="max_length", truncation=True)
+... start_positions = []
+... end_positions = []
+
+... # 배치의 예제를 반복합니다
+... for i in range(len(questions)):
+... cls_index = encoding["input_ids"][i].index(tokenizer.cls_token_id)
+
+... # 예제의 words에서 답변의 위치를 찾습니다
+... words_example = [word.lower() for word in words[i]]
+... answer = answers[i]
+... match, word_idx_start, word_idx_end = subfinder(words_example, answer.lower().split())
+
+... if match:
+... # 일치하는 항목을 발견하면, `token_type_ids`를 사용해 인코딩에서 단어가 시작하는 위치를 찾습니다
+... token_type_ids = encoding["token_type_ids"][i]
+... token_start_index = 0
+... while token_type_ids[token_start_index] != 1:
+... token_start_index += 1
+
+... token_end_index = len(encoding["input_ids"][i]) - 1
+... while token_type_ids[token_end_index] != 1:
+... token_end_index -= 1
+
+... word_ids = encoding.word_ids(i)[token_start_index : token_end_index + 1]
+... start_position = cls_index
+... end_position = cls_index
+
+... # words의 답변 위치와 일치할 때까지 word_ids를 반복하고 `token_start_index`를 늘립니다
+... # 일치하면 `token_start_index`를 인코딩에서 답변의 `start_position`으로 저장합니다
+... for id in word_ids:
+... if id == word_idx_start:
+... start_position = token_start_index
+... else:
+... token_start_index += 1
+
+... # 비슷하게, 끝에서 시작해 `word_ids`를 반복하며 답변의 `end_position`을 찾습니다
+... for id in word_ids[::-1]:
+... if id == word_idx_end:
+... end_position = token_end_index
+... else:
+... token_end_index -= 1
+
+... start_positions.append(start_position)
+... end_positions.append(end_position)
+
+... else:
+... start_positions.append(cls_index)
+... end_positions.append(cls_index)
+
+... encoding["image"] = examples["image"]
+... encoding["start_positions"] = start_positions
+... encoding["end_positions"] = end_positions
+
+... return encoding
+```
+
+이제 이 전처리 함수가 있으니 전체 데이터 세트를 인코딩할 수 있습니다:
+
+```py
+>>> encoded_train_dataset = dataset_with_ocr["train"].map(
+... encode_dataset, batched=True, batch_size=2, remove_columns=dataset_with_ocr["train"].column_names
+... )
+>>> encoded_test_dataset = dataset_with_ocr["test"].map(
+... encode_dataset, batched=True, batch_size=2, remove_columns=dataset_with_ocr["test"].column_names
+... )
+```
+
+인코딩된 데이터 세트의 특성이 어떻게 생겼는지 확인해 보겠습니다:
+
+```py
+>>> encoded_train_dataset.features
+{'image': Sequence(feature=Sequence(feature=Sequence(feature=Value(dtype='uint8', id=None), length=-1, id=None), length=-1, id=None), length=-1, id=None),
+ 'input_ids': Sequence(feature=Value(dtype='int32', id=None), length=-1, id=None),
+ 'token_type_ids': Sequence(feature=Value(dtype='int8', id=None), length=-1, id=None),
+ 'attention_mask': Sequence(feature=Value(dtype='int8', id=None), length=-1, id=None),
+ 'bbox': Sequence(feature=Sequence(feature=Value(dtype='int64', id=None), length=-1, id=None), length=-1, id=None),
+ 'start_positions': Value(dtype='int64', id=None),
+ 'end_positions': Value(dtype='int64', id=None)}
+```
+
+## 평가 [[evaluation]]
+
+문서 질의 응답을 평가하려면 상당한 양의 후처리가 필요합니다. 시간이 너무 많이 걸리지 않도록 이 가이드에서는 평가 단계를 생략합니다.
+[`Trainer`]가 훈련 과정에서 평가 손실(evaluation loss)을 계속 계산하기 때문에 모델의 성능을 대략적으로 알 수 있습니다.
+추출적(Extractive) 질의 응답은 보통 F1/exact match 방법을 사용해 평가됩니다.
+직접 구현해보고 싶으시다면, Hugging Face course의 [Question Answering chapter](https://huggingface.co/course/chapter7/7?fw=pt#postprocessing)을 참고하세요.
+
+## 훈련 [[train]]
+
+축하합니다! 이 가이드의 가장 어려운 부분을 성공적으로 처리했으니 이제 나만의 모델을 훈련할 준비가 되었습니다.
+훈련은 다음과 같은 단계로 이루어져 있습니다:
+* 전처리에서의 동일한 체크포인트를 사용하기 위해 [`AutoModelForDocumentQuestionAnswering`]으로 모델을 가져옵니다.
+* [`TrainingArguments`]로 훈련 하이퍼파라미터를 정합니다.
+* 예제를 배치 처리하는 함수를 정의합니다. 여기서는 [`DefaultDataCollator`]가 적당합니다.
+* 모델, 데이터 세트, 데이터 콜레이터(Data collator)와 함께 [`Trainer`]에 훈련 인수들을 전달합니다.
+* [`~Trainer.train`]을 호출해서 모델을 미세 조정합니다.
+
+```py
+>>> from transformers import AutoModelForDocumentQuestionAnswering
+
+>>> model = AutoModelForDocumentQuestionAnswering.from_pretrained(model_checkpoint)
+```
+
+[`TrainingArguments`]에서 `output_dir`을 사용하여 모델을 저장할 위치를 지정하고, 적절한 하이퍼파라미터를 설정합니다.
+모델을 커뮤니티와 공유하려면 `push_to_hub`를 `True`로 설정하세요 (모델을 업로드하려면 Hugging Face에 로그인해야 합니다).
+이 경우 `output_dir`은 모델의 체크포인트를 푸시할 레포지토리의 이름이 됩니다.
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> # 본인의 레포지토리 ID로 바꾸세요
+>>> repo_id = "MariaK/layoutlmv2-base-uncased_finetuned_docvqa"
+
+>>> training_args = TrainingArguments(
+... output_dir=repo_id,
+... per_device_train_batch_size=4,
+... num_train_epochs=20,
+... save_steps=200,
+... logging_steps=50,
+... eval_strategy="steps",
+... learning_rate=5e-5,
+... save_total_limit=2,
+... remove_unused_columns=False,
+... push_to_hub=True,
+... )
+```
+
+간단한 데이터 콜레이터를 정의하여 예제를 함께 배치합니다.
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+마지막으로, 모든 것을 한 곳에 모아 [`~Trainer.train`]을 호출합니다:
+
+```py
+>>> from transformers import Trainer
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... data_collator=data_collator,
+... train_dataset=encoded_train_dataset,
+... eval_dataset=encoded_test_dataset,
+... processing_class=processor,
+... )
+
+>>> trainer.train()
+```
+
+최종 모델을 🤗 Hub에 추가하려면, 모델 카드를 생성하고 `push_to_hub`를 호출합니다:
+
+```py
+>>> trainer.create_model_card()
+>>> trainer.push_to_hub()
+```
+
+## 추론 [[inference]]
+
+이제 LayoutLMv2 모델을 미세 조정하고 🤗 Hub에 업로드했으니 추론에도 사용할 수 있습니다.
+추론을 위해 미세 조정된 모델을 사용해 보는 가장 간단한 방법은 [`Pipeline`]을 사용하는 것 입니다.
+
+예를 들어 보겠습니다:
+```py
+>>> example = dataset["test"][2]
+>>> question = example["query"]["en"]
+>>> image = example["image"]
+>>> print(question)
+>>> print(example["answers"])
+'Who is ‘presiding’ TRRF GENERAL SESSION (PART 1)?'
+['TRRF Vice President', 'lee a. waller']
+```
+
+그 다음, 모델로 문서 질의 응답을 하기 위해 파이프라인을 인스턴스화하고 이미지 + 질문 조합을 전달합니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> qa_pipeline = pipeline("document-question-answering", model="MariaK/layoutlmv2-base-uncased_finetuned_docvqa")
+>>> qa_pipeline(image, question)
+[{'score': 0.9949808120727539,
+ 'answer': 'Lee A. Waller',
+ 'start': 55,
+ 'end': 57}]
+```
+
+원한다면 파이프라인의 결과를 수동으로 복제할 수도 있습니다:
+1. 이미지와 질문을 가져와 모델의 프로세서를 사용해 모델에 맞게 준비합니다.
+2. 모델을 통해 결과 또는 전처리를 전달합니다.
+3. 모델은 어떤 토큰이 답변의 시작에 있는지, 어떤 토큰이 답변이 끝에 있는지를 나타내는 `start_logits`와 `end_logits`를 반환합니다. 둘 다 (batch_size, sequence_length) 형태를 갖습니다.
+4. `start_logits`와 `end_logits`의 마지막 차원을 최대로 만드는 값을 찾아 예상 `start_idx`와 `end_idx`를 얻습니다.
+5. 토크나이저로 답변을 디코딩합니다.
+
+```py
+>>> import torch
+>>> from transformers import AutoProcessor
+>>> from transformers import AutoModelForDocumentQuestionAnswering
+
+>>> processor = AutoProcessor.from_pretrained("MariaK/layoutlmv2-base-uncased_finetuned_docvqa")
+>>> model = AutoModelForDocumentQuestionAnswering.from_pretrained("MariaK/layoutlmv2-base-uncased_finetuned_docvqa")
+
+>>> with torch.no_grad():
+... encoding = processor(image.convert("RGB"), question, return_tensors="pt")
+... outputs = model(**encoding)
+... start_logits = outputs.start_logits
+... end_logits = outputs.end_logits
+... predicted_start_idx = start_logits.argmax(-1).item()
+... predicted_end_idx = end_logits.argmax(-1).item()
+
+>>> processor.tokenizer.decode(encoding.input_ids.squeeze()[predicted_start_idx : predicted_end_idx + 1])
+'lee a. waller'
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/idefics.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/idefics.md
new file mode 100644
index 0000000000000000000000000000000000000000..40dc794ecc141e14e52d02da3f61c05b7ddac43b
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/idefics.md
@@ -0,0 +1,391 @@
+
+
+# IDEFICS를 이용한 이미지 작업[[image-tasks-with-idefics]]
+
+[[open-in-colab]]
+
+개별 작업은 특화된 모델을 미세 조정하여 처리할 수 있지만, 최근 등장하여 인기를 얻고 있는 방식은 대규모 모델을 미세 조정 없이 다양한 작업에 사용하는 것입니다. 예를 들어, 대규모 언어 모델은 요약, 번역, 분류 등과 같은 자연어처리 (NLP) 작업을 처리할 수 있습니다. 이 접근 방식은 텍스트와 같은 단일 모달리티에 국한되지 않으며, 이 가이드에서는 IDEFICS라는 대규모 멀티모달 모델을 사용하여 이미지-텍스트 작업을 다루는 방법을 설명합니다.
+
+[IDEFICS](../model_doc/idefics)는 [Flamingo](https://huggingface.co/papers/2204.14198)를 기반으로 하는 오픈 액세스 비전 및 언어 모델로, DeepMind에서 처음 개발한 최신 시각 언어 모델입니다. 이 모델은 임의의 이미지 및 텍스트 입력 시퀀스를 받아 일관성 있는 텍스트를 출력으로 생성합니다. 이미지에 대한 질문에 답변하고, 시각적인 내용을 설명하며, 여러 이미지에 기반한 이야기를 생성하는 등 다양한 작업을 수행할 수 있습니다. IDEFICS는 [800억 파라미터](https://huggingface.co/HuggingFaceM4/idefics-80b)와 [90억 파라미터](https://huggingface.co/HuggingFaceM4/idefics-9b) 두 가지 버전을 제공하며, 두 버전 모두 🤗 Hub에서 이용할 수 있습니다. 각 버전에는 대화형 사용 사례에 맞게 미세 조정된 버전도 있습니다.
+
+이 모델은 매우 다재다능하며 광범위한 이미지 및 멀티모달 작업에 사용될 수 있습니다. 그러나 대규모 모델이기 때문에 상당한 컴퓨팅 자원과 인프라가 필요합니다. 각 개별 작업에 특화된 모델을 미세 조정하는 것보다 모델을 그대로 사용하는 것이 더 적합한지는 사용자가 판단해야 합니다.
+
+이 가이드에서는 다음을 배우게 됩니다:
+- [IDEFICS 로드하기](#loading-the-model) 및 [양자화된 버전의 모델 로드하기](#quantized-model)
+- IDEFICS를 사용하여:
+ - [이미지 캡셔닝](#image-captioning)
+ - [프롬프트 이미지 캡셔닝](#prompted-image-captioning)
+ - [퓨샷 프롬프트](#few-shot-prompting)
+ - [시각적 질의 응답](#visual-question-answering)
+ - [이미지 분류](#image-classification)
+ - [이미지 기반 텍스트 생성](#image-guided-text-generation)
+- [배치 모드에서 추론 실행](#running-inference-in-batch-mode)
+- [대화형 사용을 위한 IDEFICS 인스트럭트 실행](#idefics-instruct-for-conversational-use)
+
+시작하기 전에 필요한 모든 라이브러리가 설치되어 있는지 확인하세요.
+
+```bash
+pip install -q bitsandbytes sentencepiece accelerate transformers
+```
+
+
+다음 예제를 비양자화된 버전의 모델 체크포인트로 실행하려면 최소 20GB의 GPU 메모리가 필요합니다.
+
+
+## 모델 로드[[loading-the-model]]
+
+모델을 90억 파라미터 버전의 체크포인트로 로드해 봅시다:
+
+```py
+>>> checkpoint = "HuggingFaceM4/idefics-9b"
+```
+
+다른 Transformers 모델과 마찬가지로, 체크포인트에서 프로세서와 모델 자체를 로드해야 합니다.
+IDEFICS 프로세서는 [`LlamaTokenizer`]와 IDEFICS 이미지 프로세서를 하나의 프로세서로 감싸서 텍스트와 이미지 입력을 모델에 맞게 준비합니다.
+
+```py
+>>> import torch
+
+>>> from transformers import IdeficsForVisionText2Text, AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+
+>>> model = IdeficsForVisionText2Text.from_pretrained(checkpoint, torch_dtype=torch.bfloat16, device_map="auto")
+```
+
+`device_map`을 `"auto"`로 설정하면 사용 중인 장치를 고려하여 모델 가중치를 가장 최적화된 방식으로 로드하고 저장하는 방법을 자동으로 결정합니다.
+
+### 양자화된 모델[[quantized-model]]
+
+고용량 GPU 사용이 어려운 경우, 모델의 양자화된 버전을 로드할 수 있습니다. 모델과 프로세서를 4비트 정밀도로 로드하기 위해서, `from_pretrained` 메소드에 `BitsAndBytesConfig`를 전달하면 모델이 로드되는 동안 실시간으로 압축됩니다.
+
+```py
+>>> import torch
+>>> from transformers import IdeficsForVisionText2Text, AutoProcessor, BitsAndBytesConfig
+
+>>> quantization_config = BitsAndBytesConfig(
+... load_in_4bit=True,
+... bnb_4bit_compute_dtype=torch.float16,
+... )
+
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+
+>>> model = IdeficsForVisionText2Text.from_pretrained(
+... checkpoint,
+... quantization_config=quantization_config,
+... device_map="auto"
+... )
+```
+
+이제 모델을 제안된 방법 중 하나로 로드했으니, IDEFICS를 사용할 수 있는 작업들을 탐구해봅시다.
+
+## 이미지 캡셔닝[[image-captioning]]
+이미지 캡셔닝은 주어진 이미지에 대한 캡션을 예측하는 작업입니다. 일반적인 응용 분야는 시각 장애인이 다양한 상황을 탐색할 수 있도록 돕는 것입니다. 예를 들어, 온라인에서 이미지 콘텐츠를 탐색하는 데 도움을 줄 수 있습니다.
+
+작업을 설명하기 위해 캡션을 달 이미지 예시를 가져옵니다. 예시:
+
+
+
+
+
+사진 제공: [Hendo Wang](https://unsplash.com/@hendoo).
+
+IDEFICS는 텍스트 및 이미지 프롬프트를 모두 수용합니다. 그러나 이미지를 캡션하기 위해 모델에 텍스트 프롬프트를 제공할 필요는 없습니다. 전처리된 입력 이미지만 제공하면 됩니다. 텍스트 프롬프트 없이 모델은 BOS(시퀀스 시작) 토큰부터 텍스트 생성을 시작하여 캡션을 만듭니다.
+
+모델에 이미지 입력으로는 이미지 객체(`PIL.Image`) 또는 이미지를 가져올 수 있는 URL을 사용할 수 있습니다.
+
+```py
+>>> prompt = [
+... "https://images.unsplash.com/photo-1583160247711-2191776b4b91?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3542&q=80",
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+A puppy in a flower bed
+```
+
+
+
+`max_new_tokens`의 크기를 증가시킬 때 발생할 수 있는 오류를 피하기 위해 `generate` 호출 시 `bad_words_ids`를 포함하는 것이 좋습니다. 모델로부터 생성된 이미지가 없을 때 새로운 `` 또는 `` 토큰을 생성하려고 하기 때문입니다.
+이 가이드에서처럼 `bad_words_ids`를 함수 호출 시에 매개변수로 설정하거나, [텍스트 생성 전략](../generation_strategies) 가이드에 설명된 대로 `GenerationConfig`에 저장할 수도 있습니다.
+
+
+## 프롬프트 이미지 캡셔닝[[prompted-image-captioning]]
+
+텍스트 프롬프트를 이용하여 이미지 캡셔닝을 확장할 수 있으며, 모델은 주어진 이미지를 바탕으로 텍스트를 계속 생성합니다. 다음 이미지를 예시로 들어보겠습니다:
+
+
+
+
+
+사진 제공: [Denys Nevozhai](https://unsplash.com/@dnevozhai).
+
+텍스트 및 이미지 프롬프트는 적절한 입력을 생성하기 위해 모델의 프로세서에 하나의 목록으로 전달될 수 있습니다.
+
+```py
+>>> prompt = [
+... "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
+... "This is an image of ",
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+This is an image of the Eiffel Tower in Paris, France.
+```
+
+## 퓨샷 프롬프트[[few-shot-prompting]]
+
+IDEFICS는 훌륭한 제로샷 결과를 보여주지만, 작업에 특정 형식의 캡션이 필요하거나 작업의 복잡성을 높이는 다른 제한 사항이나 요구 사항이 있을 수 있습니다. 이럴 때 퓨샷 프롬프트를 사용하여 맥락 내 학습(In-Context Learning)을 가능하게 할 수 있습니다.
+프롬프트에 예시를 제공함으로써 모델이 주어진 예시의 형식을 모방한 결과를 생성하도록 유도할 수 있습니다.
+
+이전의 에펠탑 이미지를 모델에 예시로 사용하고, 모델에게 이미지의 객체를 학습하는 것 외에도 흥미로운 정보를 얻고 싶다는 것을 보여주는 프롬프트를 작성해 봅시다.
+그런 다음 자유의 여신상 이미지에 대해 동일한 응답 형식을 얻을 수 있는지 확인해 봅시다:
+
+
+
+
+
+사진 제공: [Juan Mayobre](https://unsplash.com/@jmayobres).
+
+```py
+>>> prompt = ["User:",
+... "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
+... "Describe this image.\nAssistant: An image of the Eiffel Tower at night. Fun fact: the Eiffel Tower is the same height as an 81-storey building.\n",
+... "User:",
+... "https://images.unsplash.com/photo-1524099163253-32b7f0256868?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3387&q=80",
+... "Describe this image.\nAssistant:"
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=30, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+User: Describe this image.
+Assistant: An image of the Eiffel Tower at night. Fun fact: the Eiffel Tower is the same height as an 81-storey building.
+User: Describe this image.
+Assistant: An image of the Statue of Liberty. Fun fact: the Statue of Liberty is 151 feet tall.
+```
+
+단 하나의 예시만으로도(즉, 1-shot) 모델이 작업 수행 방법을 학습했다는 점이 주목할 만합니다. 더 복잡한 작업의 경우, 더 많은 예시(예: 3-shot, 5-shot 등)를 사용하여 실험해 보는 것도 좋은 방법입니다.
+
+## 시각적 질의 응답[[visual-question-answering]]
+
+시각적 질의 응답(VQA)은 이미지를 기반으로 개방형 질문에 답하는 작업입니다. 이미지 캡셔닝과 마찬가지로 접근성 애플리케이션에서 사용할 수 있지만, 교육(시각 자료에 대한 추론), 고객 서비스(이미지를 기반으로 한 제품 질문), 이미지 검색 등에서도 사용할 수 있습니다.
+
+이 작업을 위해 새로운 이미지를 가져옵니다:
+
+
+
+
+
+사진 제공: [Jarritos Mexican Soda](https://unsplash.com/@jarritos).
+
+적절한 지시문을 사용하면 이미지 캡셔닝에서 시각적 질의 응답으로 모델을 유도할 수 있습니다:
+
+```py
+>>> prompt = [
+... "Instruction: Provide an answer to the question. Use the image to answer.\n",
+... "https://images.unsplash.com/photo-1623944889288-cd147dbb517c?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "Question: Where are these people and what's the weather like? Answer:"
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=20, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Provide an answer to the question. Use the image to answer.
+ Question: Where are these people and what's the weather like? Answer: They're in a park in New York City, and it's a beautiful day.
+```
+
+## 이미지 분류[[image-classification]]
+
+IDEFICS는 특정 카테고리의 라벨이 포함된 데이터로 명시적으로 학습되지 않아도 이미지를 다양한 카테고리로 분류할 수 있습니다. 카테고리 목록이 주어지면, 모델은 이미지와 텍스트 이해 능력을 사용하여 이미지가 속할 가능성이 높은 카테고리를 추론할 수 있습니다.
+
+여기에 야채 가판대 이미지가 있습니다.
+
+
+
+
+
+사진 제공: [Peter Wendt](https://unsplash.com/@peterwendt).
+
+우리는 모델에게 우리가 가진 카테고리 중 하나로 이미지를 분류하도록 지시할 수 있습니다:
+
+```py
+>>> categories = ['animals','vegetables', 'city landscape', 'cars', 'office']
+>>> prompt = [f"Instruction: Classify the following image into a single category from the following list: {categories}.\n",
+... "https://images.unsplash.com/photo-1471193945509-9ad0617afabf?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "Category: "
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=6, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Classify the following image into a single category from the following list: ['animals', 'vegetables', 'city landscape', 'cars', 'office'].
+Category: Vegetables
+```
+
+위 예제에서는 모델에게 이미지를 단일 카테고리로 분류하도록 지시했지만, 순위 분류를 하도록 모델에 프롬프트를 제공할 수도 있습니다.
+
+## 이미지 기반 텍스트 생성[[image-guided-text-generation]]
+
+이미지를 활용한 텍스트 생성 기술을 사용하면 더욱 창의적인 작업이 가능합니다. 이 기술은 이미지를 바탕으로 텍스트를 만들어내며, 제품 설명, 광고 문구, 장면 묘사 등 다양한 용도로 활용할 수 있습니다.
+
+간단한 예로, 빨간 문 이미지를 IDEFICS에 입력하여 이야기를 만들어보겠습니다:
+
+
+
+
+
+사진 제공: [Craig Tidball](https://unsplash.com/@devonshiremedia).
+
+```py
+>>> prompt = ["Instruction: Use the image to write a story. \n",
+... "https://images.unsplash.com/photo-1517086822157-2b0358e7684a?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=2203&q=80",
+... "Story: \n"]
+
+>>> inputs = processor(prompt, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, num_beams=2, max_new_tokens=200, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Use the image to write a story.
+ Story:
+Once upon a time, there was a little girl who lived in a house with a red door. She loved her red door. It was the prettiest door in the whole world.
+
+One day, the little girl was playing in her yard when she noticed a man standing on her doorstep. He was wearing a long black coat and a top hat.
+
+The little girl ran inside and told her mother about the man.
+
+Her mother said, “Don’t worry, honey. He’s just a friendly ghost.”
+
+The little girl wasn’t sure if she believed her mother, but she went outside anyway.
+
+When she got to the door, the man was gone.
+
+The next day, the little girl was playing in her yard again when she noticed the man standing on her doorstep.
+
+He was wearing a long black coat and a top hat.
+
+The little girl ran
+```
+
+IDEFICS가 문 앞에 있는 호박을 보고 유령에 대한 으스스한 할로윈 이야기를 만든 것 같습니다.
+
+
+
+이처럼 긴 텍스트를 생성할 때는 텍스트 생성 전략을 조정하는 것이 좋습니다. 이렇게 하면 생성된 결과물의 품질을 크게 향상시킬 수 있습니다. 자세한 내용은 [텍스트 생성 전략](../generation_strategies)을 참조하세요.
+
+
+## 배치 모드에서 추론 실행[[running-inference-in-batch-mode]]
+
+앞선 모든 섹션에서는 단일 예시에 대해 IDEFICS를 설명했습니다. 이와 매우 유사한 방식으로, 프롬프트 목록을 전달하여 여러 예시에 대한 추론을 실행할 수 있습니다:
+
+```py
+>>> prompts = [
+... [ "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
+... "This is an image of ",
+... ],
+... [ "https://images.unsplash.com/photo-1623944889288-cd147dbb517c?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "This is an image of ",
+... ],
+... [ "https://images.unsplash.com/photo-1471193945509-9ad0617afabf?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "This is an image of ",
+... ],
+... ]
+
+>>> inputs = processor(prompts, return_tensors="pt").to("cuda")
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> for i,t in enumerate(generated_text):
+... print(f"{i}:\n{t}\n")
+0:
+This is an image of the Eiffel Tower in Paris, France.
+
+1:
+This is an image of a couple on a picnic blanket.
+
+2:
+This is an image of a vegetable stand.
+```
+
+## 대화형 사용을 위한 IDEFICS 인스트럭트 실행[[idefics-instruct-for-conversational-use]]
+
+대화형 사용 사례를 위해, 🤗 Hub에서 명령어 수행에 최적화된 버전의 모델을 찾을 수 있습니다. 이곳에는 `HuggingFaceM4/idefics-80b-instruct`와 `HuggingFaceM4/idefics-9b-instruct`가 있습니다.
+
+이 체크포인트는 지도 학습 및 명령어 미세 조정 데이터셋의 혼합으로 각각의 기본 모델을 미세 조정한 결과입니다. 이를 통해 모델의 하위 작업 성능을 향상시키는 동시에 대화형 환경에서 모델을 더 사용하기 쉽게 합니다.
+
+대화형 사용을 위한 사용법 및 프롬프트는 기본 모델을 사용하는 것과 매우 유사합니다.
+
+```py
+>>> import torch
+>>> from transformers import IdeficsForVisionText2Text, AutoProcessor
+
+>>> device = "cuda" if torch.cuda.is_available() else "cpu"
+
+>>> checkpoint = "HuggingFaceM4/idefics-9b-instruct"
+>>> model = IdeficsForVisionText2Text.from_pretrained(checkpoint, torch_dtype=torch.bfloat16).to(device)
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+
+>>> prompts = [
+... [
+... "User: What is in this image?",
+... "https://upload.wikimedia.org/wikipedia/commons/8/86/Id%C3%A9fix.JPG",
+... "",
+
+... "\nAssistant: This picture depicts Idefix, the dog of Obelix in Asterix and Obelix. Idefix is running on the ground.",
+
+... "\nUser:",
+... "https://static.wikia.nocookie.net/asterix/images/2/25/R22b.gif/revision/latest?cb=20110815073052",
+... "And who is that?",
+
+... "\nAssistant:",
+... ],
+... ]
+
+>>> # --batched mode
+>>> inputs = processor(prompts, add_end_of_utterance_token=False, return_tensors="pt").to(device)
+>>> # --single sample mode
+>>> # inputs = processor(prompts[0], return_tensors="pt").to(device)
+
+>>> # args 생성
+>>> exit_condition = processor.tokenizer("", add_special_tokens=False).input_ids
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, eos_token_id=exit_condition, bad_words_ids=bad_words_ids, max_length=100)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> for i, t in enumerate(generated_text):
+... print(f"{i}:\n{t}\n")
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/image_captioning.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/image_captioning.md
new file mode 100644
index 0000000000000000000000000000000000000000..c4d0f99b6170ee067c49a2a6bf7734617bb5851f
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/image_captioning.md
@@ -0,0 +1,281 @@
+
+
+
+# 이미지 캡셔닝[[image-captioning]]
+
+[[open-in-colab]]
+
+이미지 캡셔닝(Image captioning)은 주어진 이미지에 대한 캡션을 예측하는 작업입니다.
+이미지 캡셔닝은 시각 장애인이 다양한 상황을 탐색하는 데 도움을 줄 수 있도록 시각 장애인을 보조하는 등 실생활에서 흔히 활용됩니다.
+따라서 이미지 캡셔닝은 이미지를 설명함으로써 사람들의 콘텐츠 접근성을 개선하는 데 도움이 됩니다.
+
+이 가이드에서는 소개할 내용은 아래와 같습니다:
+
+* 이미지 캡셔닝 모델을 파인튜닝합니다.
+* 파인튜닝된 모델을 추론에 사용합니다.
+
+시작하기 전에 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate -q
+pip install jiwer -q
+```
+
+Hugging Face 계정에 로그인하면 모델을 업로드하고 커뮤니티에 공유할 수 있습니다.
+토큰을 입력하여 로그인하세요.
+
+
+```python
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+## 포켓몬 BLIP 캡션 데이터세트 가져오기[[load-the-pokmon-blip-captions-dataset]]
+
+{이미지-캡션} 쌍으로 구성된 데이터세트를 가져오려면 🤗 Dataset 라이브러리를 사용합니다.
+PyTorch에서 자신만의 이미지 캡션 데이터세트를 만들려면 [이 노트북](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/GIT/Fine_tune_GIT_on_an_image_captioning_dataset.ipynb)을 참조하세요.
+
+
+```python
+from datasets import load_dataset
+
+ds = load_dataset("lambdalabs/pokemon-blip-captions")
+ds
+```
+```bash
+DatasetDict({
+ train: Dataset({
+ features: ['image', 'text'],
+ num_rows: 833
+ })
+})
+```
+
+이 데이터세트는 `image`와 `text`라는 두 특성을 가지고 있습니다.
+
+
+
+많은 이미지 캡션 데이터세트에는 이미지당 여러 개의 캡션이 포함되어 있습니다.
+이러한 경우, 일반적으로 학습 중에 사용 가능한 캡션 중에서 무작위로 샘플을 추출합니다.
+
+
+
+[`~datasets.Dataset.train_test_split`] 메소드를 사용하여 데이터세트의 학습 분할을 학습 및 테스트 세트로 나눕니다:
+
+
+```python
+ds = ds["train"].train_test_split(test_size=0.1)
+train_ds = ds["train"]
+test_ds = ds["test"]
+```
+
+학습 세트의 샘플 몇 개를 시각화해 봅시다.
+Let's visualize a couple of samples from the training set.
+
+
+```python
+from textwrap import wrap
+import matplotlib.pyplot as plt
+import numpy as np
+
+
+def plot_images(images, captions):
+ plt.figure(figsize=(20, 20))
+ for i in range(len(images)):
+ ax = plt.subplot(1, len(images), i + 1)
+ caption = captions[i]
+ caption = "\n".join(wrap(caption, 12))
+ plt.title(caption)
+ plt.imshow(images[i])
+ plt.axis("off")
+
+
+sample_images_to_visualize = [np.array(train_ds[i]["image"]) for i in range(5)]
+sample_captions = [train_ds[i]["text"] for i in range(5)]
+plot_images(sample_images_to_visualize, sample_captions)
+```
+
+
+
+
+
+## 데이터세트 전처리[[preprocess-the-dataset]]
+
+데이터세트에는 이미지와 텍스트라는 두 가지 양식이 있기 때문에, 전처리 파이프라인에서 이미지와 캡션을 모두 전처리합니다.
+
+전처리 작업을 위해, 파인튜닝하려는 모델에 연결된 프로세서 클래스를 가져옵니다.
+
+```python
+from transformers import AutoProcessor
+
+checkpoint = "microsoft/git-base"
+processor = AutoProcessor.from_pretrained(checkpoint)
+```
+
+프로세서는 내부적으로 크기 조정 및 픽셀 크기 조정을 포함한 이미지 전처리를 수행하고 캡션을 토큰화합니다.
+
+```python
+def transforms(example_batch):
+ images = [x for x in example_batch["image"]]
+ captions = [x for x in example_batch["text"]]
+ inputs = processor(images=images, text=captions, padding="max_length")
+ inputs.update({"labels": inputs["input_ids"]})
+ return inputs
+
+
+train_ds.set_transform(transforms)
+test_ds.set_transform(transforms)
+```
+
+데이터세트가 준비되었으니 이제 파인튜닝을 위해 모델을 설정할 수 있습니다.
+
+## 기본 모델 가져오기[[load-a-base-model]]
+
+["microsoft/git-base"](https://huggingface.co/microsoft/git-base)를 [`AutoModelForCausalLM`](https://huggingface.co/docs/transformers/model_doc/auto#transformers.AutoModelForCausalLM) 객체로 가져옵니다.
+
+
+```python
+from transformers import AutoModelForCausalLM
+
+model = AutoModelForCausalLM.from_pretrained(checkpoint)
+```
+
+## 평가[[evaluate]]
+
+이미지 캡션 모델은 일반적으로 [Rouge 점수](https://huggingface.co/spaces/evaluate-metric/rouge) 또는 [단어 오류율(Word Error Rate)](https://huggingface.co/spaces/evaluate-metric/wer)로 평가합니다.
+이 가이드에서는 단어 오류율(WER)을 사용합니다.
+
+이를 위해 🤗 Evaluate 라이브러리를 사용합니다.
+WER의 잠재적 제한 사항 및 기타 문제점은 [이 가이드](https://huggingface.co/spaces/evaluate-metric/wer)를 참조하세요.
+
+
+```python
+from evaluate import load
+import torch
+
+wer = load("wer")
+
+
+def compute_metrics(eval_pred):
+ logits, labels = eval_pred
+ predicted = logits.argmax(-1)
+ decoded_labels = processor.batch_decode(labels, skip_special_tokens=True)
+ decoded_predictions = processor.batch_decode(predicted, skip_special_tokens=True)
+ wer_score = wer.compute(predictions=decoded_predictions, references=decoded_labels)
+ return {"wer_score": wer_score}
+```
+
+## 학습![[train!]]
+
+이제 모델 파인튜닝을 시작할 준비가 되었습니다. 이를 위해 🤗 [`Trainer`]를 사용합니다.
+
+먼저, [`TrainingArguments`]를 사용하여 학습 인수를 정의합니다.
+
+
+```python
+from transformers import TrainingArguments, Trainer
+
+model_name = checkpoint.split("/")[1]
+
+training_args = TrainingArguments(
+ output_dir=f"{model_name}-pokemon",
+ learning_rate=5e-5,
+ num_train_epochs=50,
+ fp16=True,
+ per_device_train_batch_size=32,
+ per_device_eval_batch_size=32,
+ gradient_accumulation_steps=2,
+ save_total_limit=3,
+ eval_strategy="steps",
+ eval_steps=50,
+ save_strategy="steps",
+ save_steps=50,
+ logging_steps=50,
+ remove_unused_columns=False,
+ push_to_hub=True,
+ label_names=["labels"],
+ load_best_model_at_end=True,
+)
+```
+
+학습 인수를 데이터세트, 모델과 함께 🤗 Trainer에 전달합니다.
+
+```python
+trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_ds,
+ eval_dataset=test_ds,
+ compute_metrics=compute_metrics,
+)
+```
+
+학습을 시작하려면 [`Trainer`] 객체에서 [`~Trainer.train`]을 호출하기만 하면 됩니다.
+
+```python
+trainer.train()
+```
+
+학습이 진행되면서 학습 손실이 원활하게 감소하는 것을 볼 수 있습니다.
+
+학습이 완료되면 모든 사람이 모델을 사용할 수 있도록 [`~Trainer.push_to_hub`] 메소드를 사용하여 모델을 허브에 공유하세요:
+
+
+```python
+trainer.push_to_hub()
+```
+
+## 추론[[inference]]
+
+`test_ds`에서 샘플 이미지를 가져와 모델을 테스트합니다.
+
+
+```python
+from PIL import Image
+import requests
+
+url = "https://huggingface.co/datasets/sayakpaul/sample-datasets/resolve/main/pokemon.png"
+image = Image.open(requests.get(url, stream=True).raw)
+image
+```
+
+
+
+
+
+모델에 사용할 이미지를 준비합니다.
+
+```python
+device = "cuda" if torch.cuda.is_available() else "cpu"
+
+inputs = processor(images=image, return_tensors="pt").to(device)
+pixel_values = inputs.pixel_values
+```
+
+[`generate`]를 호출하고 예측을 디코딩합니다.
+
+```python
+generated_ids = model.generate(pixel_values=pixel_values, max_length=50)
+generated_caption = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+print(generated_caption)
+```
+```bash
+a drawing of a pink and blue pokemon
+```
+
+파인튜닝된 모델이 꽤 괜찮은 캡션을 생성한 것 같습니다!
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/image_classification.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/image_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..4955bd6cdf8108624fb706a0d5c0605814858eb5
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/image_classification.md
@@ -0,0 +1,542 @@
+
+
+# 이미지 분류[[image-classification]]
+
+[[open-in-colab]]
+
+
+
+이미지 분류는 이미지에 레이블 또는 클래스를 할당합니다. 텍스트 또는 오디오 분류와 달리 입력은
+이미지를 구성하는 픽셀 값입니다. 이미지 분류에는 자연재해 후 피해 감지, 농작물 건강 모니터링, 의료 이미지에서 질병의 징후 검사 지원 등
+다양한 응용 사례가 있습니다.
+
+이 가이드에서는 다음을 설명합니다:
+
+1. [Food-101](https://huggingface.co/datasets/food101) 데이터 세트에서 [ViT](model_doc/vit)를 미세 조정하여 이미지에서 식품 항목을 분류합니다.
+2. 추론을 위해 미세 조정 모델을 사용합니다.
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/image-classification)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에, 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+Hugging Face 계정에 로그인하여 모델을 업로드하고 커뮤니티에 공유하는 것을 권장합니다. 메시지가 표시되면, 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Food-101 데이터 세트 가져오기[[load-food101-dataset]]
+
+🤗 Datasets 라이브러리에서 Food-101 데이터 세트의 더 작은 부분 집합을 가져오는 것으로 시작합니다. 이렇게 하면 전체 데이터 세트에 대한
+훈련에 많은 시간을 할애하기 전에 실험을 통해 모든 것이 제대로 작동하는지 확인할 수 있습니다.
+
+```py
+>>> from datasets import load_dataset
+
+>>> food = load_dataset("food101", split="train[:5000]")
+```
+
+데이터 세트의 `train`을 [`~datasets.Dataset.train_test_split`] 메소드를 사용하여 훈련 및 테스트 세트로 분할하세요:
+
+```py
+>>> food = food.train_test_split(test_size=0.2)
+```
+
+그리고 예시를 살펴보세요:
+
+```py
+>>> food["train"][0]
+{'image': ,
+ 'label': 79}
+```
+
+데이터 세트의 각 예제에는 두 개의 필드가 있습니다:
+
+- `image`: 식품 항목의 PIL 이미지
+- `label`: 식품 항목의 레이블 클래스
+
+모델이 레이블 ID에서 레이블 이름을 쉽게 가져올 수 있도록
+레이블 이름을 정수로 매핑하고, 정수를 레이블 이름으로 매핑하는 사전을 만드세요:
+
+```py
+>>> labels = food["train"].features["label"].names
+>>> label2id, id2label = dict(), dict()
+>>> for i, label in enumerate(labels):
+... label2id[label] = str(i)
+... id2label[str(i)] = label
+```
+
+이제 레이블 ID를 레이블 이름으로 변환할 수 있습니다:
+
+```py
+>>> id2label[str(79)]
+'prime_rib'
+```
+
+## 전처리[[preprocess]]
+
+다음 단계는 이미지를 텐서로 처리하기 위해 ViT 이미지 프로세서를 가져오는 것입니다:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> checkpoint = "google/vit-base-patch16-224-in21k"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
+```
+
+
+
+이미지에 몇 가지 이미지 변환을 적용하여 과적합에 대해 모델을 더 견고하게 만듭니다. 여기서 Torchvision의 [`transforms`](https://pytorch.org/vision/stable/transforms.html) 모듈을 사용하지만, 원하는 이미지 라이브러리를 사용할 수도 있습니다.
+
+이미지의 임의 부분을 크롭하고 크기를 조정한 다음, 이미지 평균과 표준 편차로 정규화하세요:
+
+```py
+>>> from torchvision.transforms import RandomResizedCrop, Compose, Normalize, ToTensor
+
+>>> normalize = Normalize(mean=image_processor.image_mean, std=image_processor.image_std)
+>>> size = (
+... image_processor.size["shortest_edge"]
+... if "shortest_edge" in image_processor.size
+... else (image_processor.size["height"], image_processor.size["width"])
+... )
+>>> _transforms = Compose([RandomResizedCrop(size), ToTensor(), normalize])
+```
+
+그런 다음 전처리 함수를 만들어 변환을 적용하고 이미지의 `pixel_values`(모델에 대한 입력)를 반환하세요:
+
+```py
+>>> def transforms(examples):
+... examples["pixel_values"] = [_transforms(img.convert("RGB")) for img in examples["image"]]
+... del examples["image"]
+... return examples
+```
+
+전체 데이터 세트에 전처리 기능을 적용하려면 🤗 Datasets [`~datasets.Dataset.with_transform`]을 사용합니다. 데이터 세트의 요소를 가져올 때 변환이 즉시 적용됩니다:
+
+```py
+>>> food = food.with_transform(transforms)
+```
+
+이제 [`DefaultDataCollator`]를 사용하여 예제 배치를 만듭니다. 🤗 Transformers의 다른 데이터 콜레이터와 달리, `DefaultDataCollator`는 패딩과 같은 추가적인 전처리를 적용하지 않습니다.
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+
+
+
+
+
+
+과적합을 방지하고 모델을 보다 견고하게 만들기 위해 데이터 세트의 훈련 부분에 데이터 증강을 추가합니다.
+여기서 Keras 전처리 레이어로 훈련 데이터에 대한 변환(데이터 증강 포함)과
+검증 데이터에 대한 변환(중앙 크로핑, 크기 조정, 정규화만)을 정의합니다.
+`tf.image` 또는 다른 원하는 라이브러리를 사용할 수 있습니다.
+
+```py
+>>> from tensorflow import keras
+>>> from tensorflow.keras import layers
+
+>>> size = (image_processor.size["height"], image_processor.size["width"])
+
+>>> train_data_augmentation = keras.Sequential(
+... [
+... layers.RandomCrop(size[0], size[1]),
+... layers.Rescaling(scale=1.0 / 127.5, offset=-1),
+... layers.RandomFlip("horizontal"),
+... layers.RandomRotation(factor=0.02),
+... layers.RandomZoom(height_factor=0.2, width_factor=0.2),
+... ],
+... name="train_data_augmentation",
+... )
+
+>>> val_data_augmentation = keras.Sequential(
+... [
+... layers.CenterCrop(size[0], size[1]),
+... layers.Rescaling(scale=1.0 / 127.5, offset=-1),
+... ],
+... name="val_data_augmentation",
+... )
+```
+
+다음으로 한 번에 하나의 이미지가 아니라 이미지 배치에 적절한 변환을 적용하는 함수를 만듭니다.
+
+```py
+>>> import numpy as np
+>>> import tensorflow as tf
+>>> from PIL import Image
+
+
+>>> def convert_to_tf_tensor(image: Image):
+... np_image = np.array(image)
+... tf_image = tf.convert_to_tensor(np_image)
+... # `expand_dims()` is used to add a batch dimension since
+... # the TF augmentation layers operates on batched inputs.
+... return tf.expand_dims(tf_image, 0)
+
+
+>>> def preprocess_train(example_batch):
+... """Apply train_transforms across a batch."""
+... images = [
+... train_data_augmentation(convert_to_tf_tensor(image.convert("RGB"))) for image in example_batch["image"]
+... ]
+... example_batch["pixel_values"] = [tf.transpose(tf.squeeze(image)) for image in images]
+... return example_batch
+
+
+... def preprocess_val(example_batch):
+... """Apply val_transforms across a batch."""
+... images = [
+... val_data_augmentation(convert_to_tf_tensor(image.convert("RGB"))) for image in example_batch["image"]
+... ]
+... example_batch["pixel_values"] = [tf.transpose(tf.squeeze(image)) for image in images]
+... return example_batch
+```
+
+🤗 Datasets [`~datasets.Dataset.set_transform`]를 사용하여 즉시 변환을 적용하세요:
+
+```py
+food["train"].set_transform(preprocess_train)
+food["test"].set_transform(preprocess_val)
+```
+
+최종 전처리 단계로 `DefaultDataCollator`를 사용하여 예제 배치를 만듭니다. 🤗 Transformers의 다른 데이터 콜레이터와 달리
+`DefaultDataCollator`는 패딩과 같은 추가 전처리를 적용하지 않습니다.
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+```
+
+
+
+## 평가[[evaluate]]
+
+훈련 중에 평가 지표를 포함하면 모델의 성능을 평가하는 데 도움이 되는 경우가 많습니다.
+🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리로 평가 방법을 빠르게 가져올 수 있습니다. 이 작업에서는
+[accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) 평가 지표를 가져옵니다. (🤗 Evaluate [빠른 둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하여 평가 지표를 가져오고 계산하는 방법에 대해 자세히 알아보세요):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+그런 다음 예측과 레이블을 [`~evaluate.EvaluationModule.compute`]에 전달하여 정확도를 계산하는 함수를 만듭니다:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... predictions = np.argmax(predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=labels)
+```
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었으며, 훈련을 설정하면 이 함수로 되돌아올 것입니다.
+
+## 훈련[[train]]
+
+
+
+
+
+[`Trainer`]를 사용하여 모델을 미세 조정하는 방법에 익숙하지 않은 경우, [여기](../training#train-with-pytorch-trainer)에서 기본 튜토리얼을 확인하세요!
+
+
+
+이제 모델을 훈련시킬 준비가 되었습니다! [`AutoModelForImageClassification`]로 ViT를 가져옵니다. 예상되는 레이블 수, 레이블 매핑 및 레이블 수를 지정하세요:
+
+```py
+>>> from transformers import AutoModelForImageClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForImageClassification.from_pretrained(
+... checkpoint,
+... num_labels=len(labels),
+... id2label=id2label,
+... label2id=label2id,
+... )
+```
+
+이제 세 단계만 거치면 끝입니다:
+
+1. [`TrainingArguments`]에서 훈련 하이퍼파라미터를 정의하세요. `image` 열이 삭제되기 때문에 미사용 열을 제거하지 않는 것이 중요합니다. `image` 열이 없으면 `pixel_values`을 생성할 수 없습니다. 이 동작을 방지하려면 `remove_unused_columns=False`로 설정하세요! 다른 유일한 필수 매개변수는 모델 저장 위치를 지정하는 `output_dir`입니다. `push_to_hub=True`로 설정하면 이 모델을 허브에 푸시합니다(모델을 업로드하려면 Hugging Face에 로그인해야 합니다). 각 에폭이 끝날 때마다, [`Trainer`]가 정확도를 평가하고 훈련 체크포인트를 저장합니다.
+2. [`Trainer`]에 모델, 데이터 세트, 토크나이저, 데이터 콜레이터 및 `compute_metrics` 함수와 함께 훈련 인수를 전달하세요.
+3. [`~Trainer.train`]을 호출하여 모델을 미세 조정하세요.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_food_model",
+... remove_unused_columns=False,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... learning_rate=5e-5,
+... per_device_train_batch_size=16,
+... gradient_accumulation_steps=4,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... warmup_ratio=0.1,
+... logging_steps=10,
+... load_best_model_at_end=True,
+... metric_for_best_model="accuracy",
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... data_collator=data_collator,
+... train_dataset=food["train"],
+... eval_dataset=food["test"],
+... processing_class=image_processor,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면, 모든 사람이 모델을 사용할 수 있도록 [`~transformers.Trainer.push_to_hub`] 메소드로 모델을 허브에 공유하세요:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+
+
+
+Keras를 사용하여 모델을 미세 조정하는 방법에 익숙하지 않은 경우, 먼저 [기본 튜토리얼](./training#train-a-tensorflow-model-with-keras)을 확인하세요!
+
+
+
+TensorFlow에서 모델을 미세 조정하려면 다음 단계를 따르세요:
+1. 훈련 하이퍼파라미터를 정의하고 옵티마이저와 학습률 스케쥴을 설정합니다.
+2. 사전 훈련된 모델을 인스턴스화합니다.
+3. 🤗 Dataset을 `tf.data.Dataset`으로 변환합니다.
+4. 모델을 컴파일합니다.
+5. 콜백을 추가하고 훈련을 수행하기 위해 `fit()` 메소드를 사용합니다.
+6. 커뮤니티와 공유하기 위해 모델을 🤗 Hub에 업로드합니다.
+
+하이퍼파라미터, 옵티마이저 및 학습률 스케쥴을 정의하는 것으로 시작합니다:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_epochs = 5
+>>> num_train_steps = len(food["train"]) * num_epochs
+>>> learning_rate = 3e-5
+>>> weight_decay_rate = 0.01
+
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=learning_rate,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=weight_decay_rate,
+... num_warmup_steps=0,
+... )
+```
+
+그런 다음 레이블 매핑과 함께 [`TFAuto ModelForImageClassification`]으로 ViT를 가져옵니다:
+
+```py
+>>> from transformers import TFAutoModelForImageClassification
+
+>>> model = TFAutoModelForImageClassification.from_pretrained(
+... checkpoint,
+... id2label=id2label,
+... label2id=label2id,
+... )
+```
+
+데이터 세트를 [`~datasets.Dataset.to_tf_dataset`]와 `data_collator`를 사용하여 `tf.data.Dataset` 형식으로 변환하세요:
+
+```py
+>>> # converting our train dataset to tf.data.Dataset
+>>> tf_train_dataset = food["train"].to_tf_dataset(
+... columns="pixel_values", label_cols="label", shuffle=True, batch_size=batch_size, collate_fn=data_collator
+... )
+
+>>> # converting our test dataset to tf.data.Dataset
+>>> tf_eval_dataset = food["test"].to_tf_dataset(
+... columns="pixel_values", label_cols="label", shuffle=True, batch_size=batch_size, collate_fn=data_collator
+... )
+```
+
+`compile()`를 사용하여 훈련 모델을 구성하세요:
+
+```py
+>>> from tensorflow.keras.losses import SparseCategoricalCrossentropy
+
+>>> loss = tf.keras.losses.SparseCategoricalCrossentropy(from_logits=True)
+>>> model.compile(optimizer=optimizer, loss=loss)
+```
+
+예측에서 정확도를 계산하고 모델을 🤗 Hub로 푸시하려면 [Keras callbacks](../main_classes/keras_callbacks)를 사용하세요.
+`compute_metrics` 함수를 [KerasMetricCallback](../main_classes/keras_callbacks#transformers.KerasMetricCallback)에 전달하고,
+[PushToHubCallback](../main_classes/keras_callbacks#transformers.PushToHubCallback)을 사용하여 모델을 업로드합니다:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback, PushToHubCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_eval_dataset)
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="food_classifier",
+... tokenizer=image_processor,
+... save_strategy="no",
+... )
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+이제 모델을 훈련할 준비가 되었습니다! 훈련 및 검증 데이터 세트, 에폭 수와 함께 `fit()`을 호출하고,
+콜백을 사용하여 모델을 미세 조정합니다:
+
+```py
+>>> model.fit(tf_train_dataset, validation_data=tf_eval_dataset, epochs=num_epochs, callbacks=callbacks)
+Epoch 1/5
+250/250 [==============================] - 313s 1s/step - loss: 2.5623 - val_loss: 1.4161 - accuracy: 0.9290
+Epoch 2/5
+250/250 [==============================] - 265s 1s/step - loss: 0.9181 - val_loss: 0.6808 - accuracy: 0.9690
+Epoch 3/5
+250/250 [==============================] - 252s 1s/step - loss: 0.3910 - val_loss: 0.4303 - accuracy: 0.9820
+Epoch 4/5
+250/250 [==============================] - 251s 1s/step - loss: 0.2028 - val_loss: 0.3191 - accuracy: 0.9900
+Epoch 5/5
+250/250 [==============================] - 238s 949ms/step - loss: 0.1232 - val_loss: 0.3259 - accuracy: 0.9890
+```
+
+축하합니다! 모델을 미세 조정하고 🤗 Hub에 공유했습니다. 이제 추론에 사용할 수 있습니다!
+
+
+
+
+
+
+이미지 분류를 위한 모델을 미세 조정하는 자세한 예제는 다음 [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb)을 참조하세요.
+
+
+
+## 추론[[inference]]
+
+좋아요, 이제 모델을 미세 조정했으니 추론에 사용할 수 있습니다!
+
+추론을 수행하고자 하는 이미지를 가져와봅시다:
+
+```py
+>>> ds = load_dataset("food101", split="validation[:10]")
+>>> image = ds["image"][0]
+```
+
+
+
+
+
+미세 조정 모델로 추론을 시도하는 가장 간단한 방법은 [`pipeline`]을 사용하는 것입니다. 모델로 이미지 분류를 위한 `pipeline`을 인스턴스화하고 이미지를 전달합니다:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("image-classification", model="my_awesome_food_model")
+>>> classifier(image)
+[{'score': 0.31856709718704224, 'label': 'beignets'},
+ {'score': 0.015232225880026817, 'label': 'bruschetta'},
+ {'score': 0.01519392803311348, 'label': 'chicken_wings'},
+ {'score': 0.013022331520915031, 'label': 'pork_chop'},
+ {'score': 0.012728818692266941, 'label': 'prime_rib'}]
+```
+
+원한다면, `pipeline`의 결과를 수동으로 복제할 수도 있습니다:
+
+
+
+이미지를 전처리하기 위해 이미지 프로세서를 가져오고 `input`을 PyTorch 텐서로 반환합니다:
+
+```py
+>>> from transformers import AutoImageProcessor
+>>> import torch
+
+>>> image_processor = AutoImageProcessor.from_pretrained("my_awesome_food_model")
+>>> inputs = image_processor(image, return_tensors="pt")
+```
+
+입력을 모델에 전달하고 logits을 반환합니다:
+
+```py
+>>> from transformers import AutoModelForImageClassification
+
+>>> model = AutoModelForImageClassification.from_pretrained("my_awesome_food_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+확률이 가장 높은 예측 레이블을 가져오고, 모델의 `id2label` 매핑을 사용하여 레이블로 변환합니다:
+
+```py
+>>> predicted_label = logits.argmax(-1).item()
+>>> model.config.id2label[predicted_label]
+'beignets'
+```
+
+
+
+
+
+이미지를 전처리하기 위해 이미지 프로세서를 가져오고 `input`을 TensorFlow 텐서로 반환합니다:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("MariaK/food_classifier")
+>>> inputs = image_processor(image, return_tensors="tf")
+```
+
+입력을 모델에 전달하고 logits을 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForImageClassification
+
+>>> model = TFAutoModelForImageClassification.from_pretrained("MariaK/food_classifier")
+>>> logits = model(**inputs).logits
+```
+
+확률이 가장 높은 예측 레이블을 가져오고, 모델의 `id2label` 매핑을 사용하여 레이블로 변환합니다:
+
+```py
+>>> predicted_class_id = int(tf.math.argmax(logits, axis=-1)[0])
+>>> model.config.id2label[predicted_class_id]
+'beignets'
+```
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/image_feature_extraction.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/image_feature_extraction.md
new file mode 100644
index 0000000000000000000000000000000000000000..965ea771100b5e73f55d9c03bfe9b1644d36f6bd
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/image_feature_extraction.md
@@ -0,0 +1,136 @@
+
+
+# 이미지 특징 추출[[image-feature-extraction]]
+
+[[open-in-colab]]
+
+이미지 특징 추출은 주어진 이미지에서 의미론적으로 의미 있는 특징을 추출하는 작업입니다. 이는 이미지 유사성 및 이미지 검색 등 다양한 사용 사례가 있습니다.
+게다가 대부분의 컴퓨터 비전 모델은 이미지 특징 추출에 사용할 수 있으며, 여기서 작업 특화 헤드(이미지 분류, 물체 감지 등)를 제거하고 특징을 얻을 수 있습니다. 이러한 특징은 가장자리 감지, 모서리 감지 등 고차원 수준에서 매우 유용합니다.
+또한 모델의 깊이에 따라 실제 세계에 대한 정보(예: 고양이가 어떻게 생겼는지)를 포함할 수도 있습니다. 따라서 이러한 출력은 특정 데이터 세트에 대한 새로운 분류기를 훈련하는 데 사용할 수 있습니다.
+
+이 가이드에서는:
+
+- `image-feature-extraction` 파이프라인을 활용하여 간단한 이미지 유사성 시스템을 구축하는 방법을 배웁니다.
+- 기본 모델 추론으로 동일한 작업을 수행합니다.
+
+## `image-feature-extraction` 파이프라인을 이용한 이미지 유사성[[image-similarity-using-image-feature-extraction-pipeline]]
+
+물고기 그물 위에 앉아 있는 두 장의 고양이 사진이 있습니다. 이 중 하나는 생성된 이미지입니다.
+
+```python
+from PIL import Image
+import requests
+
+img_urls = ["https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/cats.png", "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/cats.jpeg"]
+image_real = Image.open(requests.get(img_urls[0], stream=True).raw).convert("RGB")
+image_gen = Image.open(requests.get(img_urls[1], stream=True).raw).convert("RGB")
+```
+
+파이프라인을 실행해 봅시다. 먼저 파이프라인을 초기화하세요. 모델을 지정하지 않으면, 파이프라인은 자동으로 [google/vit-base-patch16-224](google/vit-base-patch16-224) 모델로 초기화됩니다. 유사도를 계산하려면 `pool`을 True로 설정하세요.
+
+
+```python
+import torch
+from transformers import pipeline
+
+DEVICE = torch.device('cuda' if torch.cuda.is_available() else 'cpu')
+pipe = pipeline(task="image-feature-extraction", model_name="google/vit-base-patch16-384", device=DEVICE, pool=True)
+```
+
+`pipe`를 사용하여 추론하려면 두 이미지를 모두 전달하세요.
+
+```python
+outputs = pipe([image_real, image_gen])
+```
+
+출력에는 두 이미지의 풀링된(pooled) 임베딩이 포함되어 있습니다.
+
+```python
+# 단일 출력의 길이 구하기
+print(len(outputs[0][0]))
+# 출력 결과 표시하기
+print(outputs)
+
+# 768
+# [[[-0.03909236937761307, 0.43381670117378235, -0.06913255900144577,
+```
+
+유사도 점수를 얻으려면, 이들을 유사도 함수에 전달해야 합니다.
+
+```python
+from torch.nn.functional import cosine_similarity
+
+similarity_score = cosine_similarity(torch.Tensor(outputs[0]),
+ torch.Tensor(outputs[1]), dim=1)
+
+print(similarity_score)
+
+# tensor([0.6043])
+```
+
+풀링 이전의 마지막 은닉 상태를 얻고 싶다면, `pool` 매개변수에 아무 값도 전달하지 마세요. 또한, 기본값은 `False`로 설정되어 있습니다. 이 은닉 상태는 모델의 특징을 기반으로 새로운 분류기나 모델을 훈련시키는 데 유용합니다.
+
+```python
+pipe = pipeline(task="image-feature-extraction", model_name="google/vit-base-patch16-224", device=DEVICE)
+output = pipe(image_real)
+```
+
+아직 출력이 풀링되지 않았기 때문에, 첫 번째 차원은 배치 크기이고 마지막 두 차원은 임베딩 형태인 마지막 은닉 상태를 얻을 수 있습니다.
+
+```python
+import numpy as np
+print(np.array(outputs).shape)
+# (1, 197, 768)
+```
+
+## `AutoModel`을 사용하여 특징과 유사성 얻기[[getting-features-and-similarities-using-automodel]]
+
+transformers의 `AutoModel` 클래스를 사용하여 특징을 얻을 수도 있습니다. `AutoModel`은 작업 특화 헤드 없이 모든 transformers 모델을 로드할 수 있으며, 이를 통해 특징을 추출할 수 있습니다.
+
+```python
+from transformers import AutoImageProcessor, AutoModel
+
+processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+model = AutoModel.from_pretrained("google/vit-base-patch16-224").to(DEVICE)
+```
+
+추론을 위한 간단한 함수를 작성해 보겠습니다. 먼저 입력값을 `processor`에 전달한 다음, 그 출력값을 `model`에 전달할 것입니다.
+
+```python
+def infer(image):
+ inputs = processor(image, return_tensors="pt").to(DEVICE)
+ outputs = model(**inputs)
+ return outputs.pooler_output
+```
+
+이 함수에 이미지를 직접 전달하여 임베딩을 얻을 수 있습니다.
+
+```python
+embed_real = infer(image_real)
+embed_gen = infer(image_gen)
+```
+
+그리고 이 임베딩을 사용하여 다시 유사도를 계산할 수 있습니다.
+
+```python
+from torch.nn.functional import cosine_similarity
+
+similarity_score = cosine_similarity(embed_real, embed_gen, dim=1)
+print(similarity_score)
+
+# tensor([0.6061], device='cuda:0', grad_fn=)
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/image_to_image.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/image_to_image.md
new file mode 100644
index 0000000000000000000000000000000000000000..f76122f78445055872188d382bec93cf3af75799
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/image_to_image.md
@@ -0,0 +1,132 @@
+
+
+# Image-to-Image 작업 가이드 [[image-to-image-task-guide]]
+
+[[open-in-colab]]
+
+Image-to-Image 작업은 애플리케이션이 이미지를 입력받아 또 다른 이미지를 출력하는 작업입니다. 여기에는 이미지 향상(초고해상도, 저조도 향상, 빗줄기 제거 등), 이미지 복원 등 다양한 하위 작업이 포함됩니다.
+
+이 가이드에서는 다음을 수행하는 방법을 보여줍니다.
+- 초고해상도 작업을 위한 image-to-image 파이프라인 사용,
+- 파이프라인 없이 동일한 작업을 위한 image-to-image 모델 실행
+
+이 가이드가 발표된 시점에서는, `image-to-image` 파이프라인은 초고해상도 작업만 지원한다는 점을 유의하세요.
+
+필요한 라이브러리를 설치하는 것부터 시작하겠습니다.
+
+```bash
+pip install transformers
+```
+
+이제 [Swin2SR 모델](https://huggingface.co/caidas/swin2SR-lightweight-x2-64)을 사용하여 파이프라인을 초기화할 수 있습니다. 그런 다음 이미지와 함께 호출하여 파이프라인으로 추론할 수 있습니다. 현재 이 파이프라인에서는 [Swin2SR 모델](https://huggingface.co/caidas/swin2SR-lightweight-x2-64)만 지원됩니다.
+
+```python
+from transformers import pipeline
+
+device = torch.device('cuda' if torch.cuda.is_available() else 'cpu')
+pipe = pipeline(task="image-to-image", model="caidas/swin2SR-lightweight-x2-64", device=device)
+```
+
+이제 이미지를 불러와 봅시다.
+
+```python
+from PIL import Image
+import requests
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/cat.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+print(image.size)
+```
+```bash
+# (532, 432)
+```
+
+
+
+
+이제 파이프라인으로 추론을 수행할 수 있습니다. 고양이 이미지의 업스케일된 버전을 얻을 수 있습니다.
+
+```python
+upscaled = pipe(image)
+print(upscaled.size)
+```
+```bash
+# (1072, 880)
+```
+
+파이프라인 없이 직접 추론을 수행하려면 Transformers의 `Swin2SRForImageSuperResolution` 및 `Swin2SRImageProcessor` 클래스를 사용할 수 있습니다. 이를 위해 동일한 모델 체크포인트를 사용합니다. 모델과 프로세서를 초기화해 보겠습니다.
+
+```python
+from transformers import Swin2SRForImageSuperResolution, Swin2SRImageProcessor
+
+model = Swin2SRForImageSuperResolution.from_pretrained("caidas/swin2SR-lightweight-x2-64").to(device)
+processor = Swin2SRImageProcessor("caidas/swin2SR-lightweight-x2-64")
+```
+
+`pipeline` 우리가 직접 수행해야 하는 전처리와 후처리 단계를 추상화하므로, 이미지를 전처리해 보겠습니다. 이미지를 프로세서에 전달한 다음 픽셀값을 GPU로 이동시키겠습니다.
+
+```python
+pixel_values = processor(image, return_tensors="pt").pixel_values
+print(pixel_values.shape)
+
+pixel_values = pixel_values.to(device)
+```
+
+이제 픽셀값을 모델에 전달하여 이미지를 추론할 수 있습니다.
+
+```python
+import torch
+
+with torch.no_grad():
+ outputs = model(pixel_values)
+```
+출력은 아래와 같은 `ImageSuperResolutionOutput` 유형의 객체입니다 👇
+
+```
+(loss=None, reconstruction=tensor([[[[0.8270, 0.8269, 0.8275, ..., 0.7463, 0.7446, 0.7453],
+ [0.8287, 0.8278, 0.8283, ..., 0.7451, 0.7448, 0.7457],
+ [0.8280, 0.8273, 0.8269, ..., 0.7447, 0.7446, 0.7452],
+ ...,
+ [0.5923, 0.5933, 0.5924, ..., 0.0697, 0.0695, 0.0706],
+ [0.5926, 0.5932, 0.5926, ..., 0.0673, 0.0687, 0.0705],
+ [0.5927, 0.5914, 0.5922, ..., 0.0664, 0.0694, 0.0718]]]],
+ device='cuda:0'), hidden_states=None, attentions=None)
+```
+`reconstruction`를 가져와 시각화를 위해 후처리해야 합니다. 어떻게 생겼는지 살펴봅시다.
+
+```python
+outputs.reconstruction.data.shape
+# torch.Size([1, 3, 880, 1072])
+```
+
+출력 텐서의 차원을 축소하고 0번째 축을 제거한 다음, 값을 클리핑하고 NumPy 부동소수점 배열로 변환해야 합니다. 그런 다음 [1072, 880] 모양을 갖도록 축을 재정렬하고 마지막으로 출력을 0과 255 사이의 값을 갖도록 되돌립니다.
+
+```python
+import numpy as np
+
+# 크기를 줄이고, CPU로 이동하고, 값을 클리핑
+output = outputs.reconstruction.data.squeeze().cpu().clamp_(0, 1).numpy()
+# 축을 재정렬
+output = np.moveaxis(output, source=0, destination=-1)
+# 값을 픽셀값 범위로 되돌리기
+output = (output * 255.0).round().astype(np.uint8)
+Image.fromarray(output)
+```
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/knowledge_distillation_for_image_classification.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/knowledge_distillation_for_image_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..37c0cc25083e0c0f8e2d298d13df18adf8c6efb6
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/knowledge_distillation_for_image_classification.md
@@ -0,0 +1,193 @@
+
+# 컴퓨터 비전을 위한 지식 증류[[Knowledge-Distillation-for-Computer-Vision]]
+
+[[open-in-colab]]
+
+지식 증류(Knowledge distillation)는 더 크고 복잡한 모델(교사)에서 더 작고 간단한 모델(학생)로 지식을 전달하는 기술입니다. 한 모델에서 다른 모델로 지식을 증류하기 위해, 특정 작업(이 경우 이미지 분류)에 대해 학습된 사전 훈련된 교사 모델을 사용하고, 랜덤으로 초기화된 학생 모델을 이미지 분류 작업에 대해 학습합니다. 그다음, 학생 모델이 교사 모델의 출력을 모방하여 두 모델의 출력 차이를 최소화하도록 훈련합니다. 이 기법은 Hinton 등 연구진의 [Distilling the Knowledge in a Neural Network](https://arxiv.org/abs/1503.02531)에서 처음 소개되었습니다. 이 가이드에서는 특정 작업에 맞춘 지식 증류를 수행할 것입니다. 이번에는 [beans dataset](https://huggingface.co/datasets/beans)을 사용할 것입니다.
+
+이 가이드는 [미세 조정된 ViT 모델](https://huggingface.co/merve/vit-mobilenet-beans-224) (교사 모델)을 [MobileNet](https://huggingface.co/google/mobilenet_v2_1.4_224) (학생 모델)으로 증류하는 방법을 🤗 Transformers의 [Trainer API](https://huggingface.co/docs/transformers/en/main_classes/trainer#trainer) 를 사용하여 보여줍니다.
+
+증류와 과정 평가를 위해 필요한 라이브러리를 설치해 봅시다.
+
+
+```bash
+pip install transformers datasets accelerate tensorboard evaluate --upgrade
+```
+
+이 예제에서는 `merve/beans-vit-224` 모델을 교사 모델로 사용하고 있습니다. 이 모델은 beans 데이터셋에서 파인 튜닝된 `google/vit-base-patch16-224-in21k` 기반의 이미지 분류 모델입니다. 이 모델을 무작위로 초기화된 MobileNetV2로 증류해볼 것입니다.
+
+이제 데이터셋을 로드하겠습니다.
+
+```python
+from datasets import load_dataset
+
+dataset = load_dataset("beans")
+```
+
+이 경우 두 모델의 이미지 프로세서가 동일한 해상도로 동일한 출력을 반환하기 때문에, 두가지를 모두 사용할 수 있습니다. 데이터셋의 모든 분할마다 전처리를 적용하기 위해 `dataset`의 `map()` 메소드를 사용할 것 입니다.
+
+
+```python
+from transformers import AutoImageProcessor
+teacher_processor = AutoImageProcessor.from_pretrained("merve/beans-vit-224")
+
+def process(examples):
+ processed_inputs = teacher_processor(examples["image"])
+ return processed_inputs
+
+processed_datasets = dataset.map(process, batched=True)
+```
+
+학생 모델(무작위로 초기화된 MobileNet)이 교사 모델(파인 튜닝된 비전 트랜스포머)을 모방하도록 할 것 입니다. 이를 위해 먼저 교사와 학생 모델의 로짓 출력값을 구합니다. 그런 다음 각 출력값을 매개변수 `temperature` 값으로 나누는데, 이 매개변수는 각 소프트 타겟의 중요도를 조절하는 역할을 합니다. 매개변수 `lambda` 는 증류 손실의 중요도에 가중치를 줍니다. 이 예제에서는 `temperature=5`와 `lambda=0.5`를 사용할 것입니다. 학생과 교사 간의 발산을 계산하기 위해 Kullback-Leibler Divergence 손실을 사용합니다. 두 데이터 P와 Q가 주어졌을 때, KL Divergence는 Q를 사용하여 P를 표현하는 데 얼만큼의 추가 정보가 필요한지를 말해줍니다. 두 데이터가 동일하다면, KL Divergence는 0이며, Q로 P를 설명하는 데 추가 정보가 필요하지 않음을 의미합니다. 따라서 지식 증류의 맥락에서 KL Divergence는 유용합니다.
+
+
+```python
+from transformers import TrainingArguments, Trainer
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+
+class ImageDistilTrainer(Trainer):
+ def __init__(self, teacher_model=None, student_model=None, temperature=None, lambda_param=None, *args, **kwargs):
+ super().__init__(model=student_model, *args, **kwargs)
+ self.teacher = teacher_model
+ self.student = student_model
+ self.loss_function = nn.KLDivLoss(reduction="batchmean")
+ device = torch.device('cuda' if torch.cuda.is_available() else 'cpu')
+ self.teacher.to(device)
+ self.teacher.eval()
+ self.temperature = temperature
+ self.lambda_param = lambda_param
+
+ def compute_loss(self, student, inputs, return_outputs=False):
+ student_output = self.student(**inputs)
+
+ with torch.no_grad():
+ teacher_output = self.teacher(**inputs)
+
+ # 교사와 학생의 소프트 타겟(soft targets) 계산
+
+ soft_teacher = F.softmax(teacher_output.logits / self.temperature, dim=-1)
+ soft_student = F.log_softmax(student_output.logits / self.temperature, dim=-1)
+
+ # 손실(loss) 계산
+ distillation_loss = self.loss_function(soft_student, soft_teacher) * (self.temperature ** 2)
+
+ # 실제 레이블 손실 계산
+ student_target_loss = student_output.loss
+
+ # 최종 손실 계산
+ loss = (1. - self.lambda_param) * student_target_loss + self.lambda_param * distillation_loss
+ return (loss, student_output) if return_outputs else loss
+```
+
+이제 Hugging Face Hub에 로그인하여 `Trainer`를 통해 Hugging Face Hub에 모델을 푸시할 수 있도록 하겠습니다.
+
+
+```python
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+이제 `TrainingArguments`, 교사 모델과 학생 모델을 설정하겠습니다.
+
+
+```python
+from transformers import AutoModelForImageClassification, MobileNetV2Config, MobileNetV2ForImageClassification
+
+training_args = TrainingArguments(
+ output_dir="my-awesome-model",
+ num_train_epochs=30,
+ fp16=True,
+ logging_dir=f"{repo_name}/logs",
+ logging_strategy="epoch",
+ eval_strategy="epoch",
+ save_strategy="epoch",
+ load_best_model_at_end=True,
+ metric_for_best_model="accuracy",
+ report_to="tensorboard",
+ push_to_hub=True,
+ hub_strategy="every_save",
+ hub_model_id=repo_name,
+ )
+
+num_labels = len(processed_datasets["train"].features["labels"].names)
+
+# 모델 초기화
+teacher_model = AutoModelForImageClassification.from_pretrained(
+ "merve/beans-vit-224",
+ num_labels=num_labels,
+ ignore_mismatched_sizes=True
+)
+
+# MobileNetV2 밑바닥부터 학습
+student_config = MobileNetV2Config()
+student_config.num_labels = num_labels
+student_model = MobileNetV2ForImageClassification(student_config)
+```
+
+`compute_metrics` 함수를 사용하여 테스트 세트에서 모델을 평가할 수 있습니다. 이 함수는 훈련 과정에서 모델의 `accuracy`와 `f1`을 계산하는 데 사용됩니다.
+
+
+```python
+import evaluate
+import numpy as np
+
+accuracy = evaluate.load("accuracy")
+
+def compute_metrics(eval_pred):
+ predictions, labels = eval_pred
+ acc = accuracy.compute(references=labels, predictions=np.argmax(predictions, axis=1))
+ return {"accuracy": acc["accuracy"]}
+```
+
+정의한 훈련 인수로 `Trainer`를 초기화해봅시다. 또한 데이터 콜레이터(data collator)를 초기화하겠습니다.
+
+```python
+from transformers import DefaultDataCollator
+
+data_collator = DefaultDataCollator()
+trainer = ImageDistilTrainer(
+ student_model=student_model,
+ teacher_model=teacher_model,
+ training_args=training_args,
+ train_dataset=processed_datasets["train"],
+ eval_dataset=processed_datasets["validation"],
+ data_collator=data_collator,
+ tokenizer=teacher_processor,
+ compute_metrics=compute_metrics,
+ temperature=5,
+ lambda_param=0.5
+)
+```
+
+이제 모델을 훈련할 수 있습니다.
+
+```python
+trainer.train()
+```
+
+모델을 테스트 세트에서 평가할 수 있습니다.
+
+```python
+trainer.evaluate(processed_datasets["test"])
+```
+
+
+테스트 세트에서 모델의 정확도는 72%에 도달했습니다. 증류의 효율성을 검증하기 위해 동일한 하이퍼파라미터로 beans 데이터셋에서 MobileNet을 처음부터 훈련하였고, 테스트 세트에서의 정확도는 63% 였습니다. 다양한 사전 훈련된 교사 모델, 학생 구조, 증류 매개변수를 시도해보시고 결과를 보고하기를 권장합니다. 증류된 모델의 훈련 로그와 체크포인트는 [이 저장소](https://huggingface.co/merve/vit-mobilenet-beans-224)에서 찾을 수 있으며, 처음부터 훈련된 MobileNetV2는 이 [저장소](https://huggingface.co/merve/resnet-mobilenet-beans-5)에서 찾을 수 있습니다.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/language_modeling.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/language_modeling.md
new file mode 100644
index 0000000000000000000000000000000000000000..1b531e49d6176df4c27e2bab1e96378535bccfc7
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/language_modeling.md
@@ -0,0 +1,411 @@
+
+
+# 인과 언어 모델링[[causal-language-modeling]]
+
+[[open-in-colab]]
+
+언어 모델링은 인과적 언어 모델링과 마스크드 언어 모델링, 두 가지 유형으로 나뉩니다. 이 가이드에서는 인과적 언어 모델링을 설명합니다.
+인과 언어 모델은 텍스트 생성에 자주 사용됩니다. 또 창의적인 방향으로 응용할 수 있습니다.
+직접 사용하며 재미있는 탐구를 해보거나, Copilot 또는 CodeParrot와 같은 지능형 코딩 어시스턴트의 기반이 되기도 합니다.
+
+
+
+인과 언어 모델링은 토큰 시퀀스에서 다음 토큰을 예측하며, 모델은 왼쪽의 토큰에만 접근할 수 있습니다.
+이는 모델이 미래의 토큰을 볼 수 없다는 것을 의미합니다. 인과 언어 모델의 예로 GPT-2가 있죠.
+
+이 가이드에서는 다음 작업을 수행하는 방법을 안내합니다:
+
+1. [DistilGPT2](https://huggingface.co/distilbert/distilgpt2) 모델을 [ELI5](https://huggingface.co/datasets/eli5) 데이터 세트의 [r/askscience](https://www.reddit.com/r/askscience/) 하위 집합으로 미세 조정
+2. 미세 조정된 모델을 추론에 사용
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/text-generation)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+커뮤니티에 모델을 업로드하고 공유하기 위해 Hugging Face 계정에 로그인하는 것을 권장합니다. 알림이 표시되면 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## ELI5 데이터 세트 불러오기[[load-eli5-dataset]]
+
+먼저, 🤗 Datasets 라이브러리에서 r/askscience의 작은 하위 집합인 ELI5 데이터 세트를 불러옵니다.
+이를 통해 전체 데이터 세트에서 학습하는 데 더 많은 시간을 투자하기 전에, 실험해봄으로써 모든 것이 작동하는지 확인할 수 있습니다.
+
+```py
+>>> from datasets import load_dataset
+
+>>> eli5 = load_dataset("eli5", split="train_asks[:5000]")
+```
+
+데이터 세트의 `train_asks` 분할을 [`~datasets.Dataset.train_test_split`] 메소드를 사용하여 학습 및 테스트 세트로 분할합니다:
+
+```py
+>>> eli5 = eli5.train_test_split(test_size=0.2)
+```
+
+그런 다음 예제를 살펴보세요:
+
+```py
+>>> eli5["train"][0]
+{'answers': {'a_id': ['c3d1aib', 'c3d4lya'],
+ 'score': [6, 3],
+ 'text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
+ "Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"]},
+ 'answers_urls': {'url': []},
+ 'document': '',
+ 'q_id': 'nyxfp',
+ 'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
+ 'selftext_urls': {'url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg']},
+ 'subreddit': 'askscience',
+ 'title': 'Few questions about this space walk photograph.',
+ 'title_urls': {'url': []}}
+```
+
+많아 보일 수 있지만, 실제로는 `text` 필드만 중요합니다. 언어 모델링 작업의 장점은 레이블이 필요하지 않다는 것입니다. 다음 단어 *자체가* 레이블입니다. (이렇게 레이블을 제공하지 않아도 되는 학습을 비지도 학습이라고 일컫습니다)
+
+## 전처리[[preprocess]]
+
+
+
+다음 단계는 `text` 필드를 전처리하기 위해 DistilGPT2 토크나이저를 불러오는 것입니다.
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilgpt2")
+```
+
+위의 예제에서 알 수 있듯이, `text` 필드는 `answers` 아래에 중첩되어 있습니다. 따라서 [`flatten`](https://huggingface.co/docs/datasets/process#flatten) 메소드를 사용하여 중첩 구조에서 `text` 하위 필드를 추출해야 합니다.
+
+```py
+>>> eli5 = eli5.flatten()
+>>> eli5["train"][0]
+{'answers.a_id': ['c3d1aib', 'c3d4lya'],
+ 'answers.score': [6, 3],
+ 'answers.text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
+ "Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"],
+ 'answers_urls.url': [],
+ 'document': '',
+ 'q_id': 'nyxfp',
+ 'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
+ 'selftext_urls.url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg'],
+ 'subreddit': 'askscience',
+ 'title': 'Few questions about this space walk photograph.',
+ 'title_urls.url': []}
+```
+
+각 하위 필드는 이제 `answers` 접두사를 가진 별도의 열로 나뉘었으며, `text` 필드는 이제 리스트입니다. 각 문장을 개별적으로 토큰화하는 대신, 먼저 리스트를 문자열로 변환하여 한꺼번에 토큰화할 수 있습니다.
+
+다음은 문자열 리스트를 결합하고 결과를 토큰화하는 첫 번째 전처리 함수입니다:
+
+```py
+>>> def preprocess_function(examples):
+... return tokenizer([" ".join(x) for x in examples["answers.text"]])
+```
+
+이 전처리 함수를 전체 데이터 세트에 적용하려면 🤗 Datasets [`~datasets.Dataset.map`] 메소드를 사용하세요. `batched=True`로 설정하여 데이터셋의 여러 요소를 한 번에 처리하고, `num_proc`를 증가시켜 프로세스 수를 늘릴 수 있습니다. 필요 없는 열은 제거하세요:
+
+```py
+>>> tokenized_eli5 = eli5.map(
+... preprocess_function,
+... batched=True,
+... num_proc=4,
+... remove_columns=eli5["train"].column_names,
+... )
+```
+
+이제 데이터 세트는 시퀀스가 토큰화됐지만, 일부 시퀀스는 모델의 최대 입력 길이보다 길 수 있습니다.
+
+이제 두 번째 전처리 함수를 사용하여
+- 모든 시퀀스를 연결하고,
+- `block_size`로 정의된 길이로 연결된 시퀀스를 여러 개의 짧은 묶음으로 나눕니다. 이 값은 최대 입력 길이와 GPU RAM을 고려해 충분히 짧아야 합니다.
+
+```py
+>>> block_size = 128
+
+
+>>> def group_texts(examples):
+... # Concatenate all texts.
+... concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
+... total_length = len(concatenated_examples[list(examples.keys())[0]])
+... # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
+... # customize this part to your needs.
+... if total_length >= block_size:
+... total_length = (total_length // block_size) * block_size
+... # Split by chunks of block_size.
+... result = {
+... k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+... for k, t in concatenated_examples.items()
+... }
+... result["labels"] = result["input_ids"].copy()
+... return result
+```
+
+전체 데이터 세트에 `group_texts` 함수를 적용하세요:
+
+```py
+>>> lm_dataset = tokenized_eli5.map(group_texts, batched=True, num_proc=4)
+```
+
+그런 다음 [`DataCollatorForLanguageModeling`]을 사용하여 예제의 배치를 만듭니다. 데이터 세트 전체를 최대 길이로 패딩하는 것보다, 취합 단계에서 각 배치의 최대 길이로 문장을 *동적으로 패딩*하는 것이 더 효율적입니다.
+
+
+
+패딩 토큰으로 종결 토큰을 사용하고 `mlm=False`로 설정하세요. 이렇게 하면 입력을 오른쪽으로 한 칸씩 시프트한 값을 레이블로 사용합니다:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> tokenizer.pad_token = tokenizer.eos_token
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False)
+```
+
+
+
+패딩 토큰으로 종결 토큰을 사용하고 `mlm=False`로 설정하세요. 이렇게 하면 입력을 오른쪽으로 한 칸씩 시프트한 값을 레이블로 사용합니다:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False, return_tensors="tf")
+```
+
+
+
+
+
+## 훈련[[train]]
+
+
+
+
+
+[`Trainer`]를 사용하여 모델을 미세 조정하는 방법을 잘 모르신다면 [기본 튜토리얼](../training#train-with-pytorch-trainer)을 확인해보세요!
+
+
+
+이제 모델을 훈련하기 준비가 되었습니다! [`AutoModelForCausalLM`]를 사용하여 DistilGPT2를 불러옵니다:
+
+```py
+>>> from transformers import AutoModelForCausalLM, TrainingArguments, Trainer
+
+>>> model = AutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+여기까지 진행하면 세 단계만 남았습니다:
+
+1. [`TrainingArguments`]에서 훈련 하이퍼파라미터를 정의하세요. `output_dir`은 유일한 필수 매개변수로, 모델을 저장할 위치를 지정합니다. (먼저 Hugging Face에 로그인 필수) `push_to_hub=True`로 설정하여 이 모델을 허브에 업로드할 수 있습니다.
+2. 훈련 인수를 [`Trainer`]에 모델, 데이터 세트 및 데이터 콜레이터와 함께 전달하세요.
+3. [`~Trainer.train`]을 호출하여 모델을 미세 조정하세요.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_eli5_clm-model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=lm_dataset["train"],
+... eval_dataset=lm_dataset["test"],
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면 [`~transformers.Trainer.evaluate`] 메소드를 사용하여 모델을 평가하고 퍼플렉서티를 얻을 수 있습니다:
+
+```py
+>>> import math
+
+>>> eval_results = trainer.evaluate()
+>>> print(f"Perplexity: {math.exp(eval_results['eval_loss']):.2f}")
+Perplexity: 49.61
+```
+
+그런 다음 [`~transformers.Trainer.push_to_hub`] 메소드를 사용하여 모델을 허브에 공유하세요. 이렇게 하면 누구나 모델을 사용할 수 있습니다:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras를 사용하여 모델을 미세 조정하는 방법에 익숙하지 않다면 [기본 튜토리얼](../training#train-a-tensorflow-model-with-keras)을 확인해보세요!
+
+
+TensorFlow에서 모델을 미세 조정하려면, 먼저 옵티마이저 함수, 학습률 스케줄 및 일부 훈련 하이퍼파라미터를 설정하세요:
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+그런 다음 [`TFAutoModelForCausalLM`]를 사용하여 DistilGPT2를 불러옵니다:
+
+```py
+>>> from transformers import TFAutoModelForCausalLM
+
+>>> model = TFAutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]을 사용하여 데이터 세트를 `tf.data.Dataset` 형식으로 변환하세요:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... lm_dataset["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... lm_dataset["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)을 사용하여 모델을 훈련하기 위해 구성하세요. Transformers 모델은 모두 기본적인 작업 관련 손실 함수를 가지고 있으므로, 원한다면 별도로 지정하지 않아도 됩니다:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # 별도로 loss 인자를 넣지 않았어요!
+```
+
+[`~transformers.PushToHubCallback`]에서 모델과 토크나이저를 업로드할 위치를 지정할 수 있습니다:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_eli5_clm-model",
+... tokenizer=tokenizer,
+... )
+```
+
+마지막으로, 모델을 훈련하기 위해 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)을 호출하세요. 훈련 데이터 세트, 검증 데이터 세트, 에폭 수 및 콜백을 전달하세요:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=[callback])
+```
+
+훈련이 완료되면 모델이 자동으로 허브에 업로드되어 모두가 사용할 수 있습니다!
+
+
+
+
+
+인과 언어 모델링을 위해 모델을 미세 조정하는 더 자세한 예제는 해당하는 [PyTorch 노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb) 또는 [TensorFlow 노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)을 참조하세요.
+
+
+
+## 추론[[inference]]
+
+좋아요, 이제 모델을 미세 조정했으므로 추론에 사용할 수 있습니다!
+
+생성할 텍스트를 위한 프롬프트를 만들어보세요:
+
+```py
+>>> prompt = "Somatic hypermutation allows the immune system to"
+```
+
+추론을 위해 미세 조정된 모델을 간단히 사용하는 가장 간단한 방법은 [`pipeline`]에서 사용하는 것입니다. 모델과 함께 텍스트 생성을 위한 `pipeline`을 인스턴스화하고 텍스트를 전달하세요:
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline("text-generation", model="my_awesome_eli5_clm-model")
+>>> generator(prompt)
+[{'generated_text': "Somatic hypermutation allows the immune system to be able to effectively reverse the damage caused by an infection.\n\n\nThe damage caused by an infection is caused by the immune system's ability to perform its own self-correcting tasks."}]
+```
+
+
+
+텍스트를 토큰화하고 `input_ids`를 PyTorch 텐서로 반환하세요:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_clm-model")
+>>> inputs = tokenizer(prompt, return_tensors="pt").input_ids
+```
+
+[`~generation.GenerationMixin.generate`] 메소드를 사용하여 텍스트를 생성하세요. 생성을 제어하는 다양한 텍스트 생성 전략과 매개변수에 대한 자세한 내용은 [텍스트 생성 전략](../generation_strategies) 페이지를 확인하세요.
+
+```py
+>>> from transformers import AutoModelForCausalLM
+
+>>> model = AutoModelForCausalLM.from_pretrained("my_awesome_eli5_clm-model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=True, top_k=50, top_p=0.95)
+```
+
+생성된 토큰 ID를 다시 텍스트로 디코딩하세요:
+
+```py
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+["Somatic hypermutation allows the immune system to react to drugs with the ability to adapt to a different environmental situation. In other words, a system of 'hypermutation' can help the immune system to adapt to a different environmental situation or in some cases even a single life. In contrast, researchers at the University of Massachusetts-Boston have found that 'hypermutation' is much stronger in mice than in humans but can be found in humans, and that it's not completely unknown to the immune system. A study on how the immune system"]
+```
+
+
+텍스트를 토큰화하고 `input_ids`를 TensorFlow 텐서로 반환하세요:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_clm-model")
+>>> inputs = tokenizer(prompt, return_tensors="tf").input_ids
+```
+
+[`~transformers.generation_tf_utils.TFGenerationMixin.generate`] 메소드를 사용하여 요약을 생성하세요. 생성을 제어하는 다양한 텍스트 생성 전략과 매개변수에 대한 자세한 내용은 [텍스트 생성 전략](../generation_strategies) 페이지를 확인하세요.
+
+```py
+>>> from transformers import TFAutoModelForCausalLM
+
+>>> model = TFAutoModelForCausalLM.from_pretrained("my_awesome_eli5_clm-model")
+>>> outputs = model.generate(input_ids=inputs, max_new_tokens=100, do_sample=True, top_k=50, top_p=0.95)
+```
+
+생성된 토큰 ID를 다시 텍스트로 디코딩하세요:
+
+```py
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Somatic hypermutation allows the immune system to detect the presence of other viruses as they become more prevalent. Therefore, researchers have identified a high proportion of human viruses. The proportion of virus-associated viruses in our study increases with age. Therefore, we propose a simple algorithm to detect the presence of these new viruses in our samples as a sign of improved immunity. A first study based on this algorithm, which will be published in Science on Friday, aims to show that this finding could translate into the development of a better vaccine that is more effective for']
+```
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/mask_generation.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/mask_generation.md
new file mode 100644
index 0000000000000000000000000000000000000000..7a937399391b7149b36a8f1d1374b3b30fc5e798
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/mask_generation.md
@@ -0,0 +1,228 @@
+
+
+# 마스크 생성[[mask-generation]]
+
+마스크 생성(Mask generation)은 이미지에 대한 의미 있는 마스크를 생성하는 작업입니다.
+이 작업은 [이미지 분할](semantic_segmentation)과 매우 유사하지만, 많은 차이점이 있습니다. 이미지 분할 모델은 라벨이 달린 데이터셋으로 학습되며, 학습 중에 본 클래스들로만 제한됩니다. 이미지가 주어지면, 이미지 분할 모델은 여러 마스크와 그에 해당하는 클래스를 반환합니다.
+
+반면, 마스크 생성 모델은 대량의 데이터로 학습되며 두 가지 모드로 작동합니다.
+- 프롬프트 모드(Prompting mode): 이 모드에서는 모델이 이미지와 프롬프트를 입력받습니다. 프롬프트는 이미지 내 객체의 2D 좌표(XY 좌표)나 객체를 둘러싼 바운딩 박스가 될 수 있습니다. 프롬프트 모드에서는 모델이 프롬프트가 가리키는 객체의 마스크만 반환합니다.
+- 전체 분할 모드(Segment Everything mode): 이 모드에서는 주어진 이미지 내에서 모든 마스크를 생성합니다. 이를 위해 그리드 형태의 점들을 생성하고 이를 이미지에 오버레이하여 추론합니다.
+
+마스크 생성 작업은 [전체 분할 모드(Segment Anything Model, SAM)](model_doc/sam)에 의해 지원됩니다. SAM은 Vision Transformer 기반 이미지 인코더, 프롬프트 인코더, 그리고 양방향 트랜스포머 마스크 디코더로 구성된 강력한 모델입니다. 이미지와 프롬프트는 인코딩되고, 디코더는 이러한 임베딩을 받아 유효한 마스크를 생성합니다.
+
+
+
+
+
+SAM은 대규모 데이터를 다룰 수 있는 강력한 분할 기반 모델입니다. 이 모델은 100만 개의 이미지와 11억 개의 마스크를 포함하는 [SA-1B](https://ai.meta.com/datasets/segment-anything/) 데이터 세트로 학습되었습니다.
+
+이 가이드에서는 다음과 같은 내용을 배우게 됩니다:
+- 배치 처리와 함께 전체 분할 모드에서 추론하는 방법
+- 포인트 프롬프팅 모드에서 추론하는 방법
+- 박스 프롬프팅 모드에서 추론하는 방법
+
+먼저, `transformers`를 설치해 봅시다:
+
+```bash
+pip install -q transformers
+```
+
+## 마스크 생성 파이프라인[[mask-generation-pipeline]]
+
+마스크 생성 모델로 추론하는 가장 쉬운 방법은 `mask-generation` 파이프라인을 사용하는 것입니다.
+
+```python
+>>> from transformers import pipeline
+
+>>> checkpoint = "facebook/sam-vit-base"
+>>> mask_generator = pipeline(model=checkpoint, task="mask-generation")
+```
+
+이미지를 예시로 봅시다.
+
+```python
+from PIL import Image
+import requests
+
+img_url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg"
+image = Image.open(requests.get(img_url, stream=True).raw).convert("RGB")
+```
+
+
+
+
+
+전체적으로 분할해봅시다. `points-per-batch`는 전체 분할 모드에서 점들의 병렬 추론을 가능하게 합니다. 이를 통해 추론 속도가 빨라지지만, 더 많은 메모리를 소모하게 됩니다. 또한, SAM은 이미지가 아닌 점들에 대해서만 배치 처리를 지원합니다. `pred_iou_thresh`는 IoU 신뢰 임계값으로, 이 임계값을 초과하는 마스크만 반환됩니다.
+
+```python
+masks = mask_generator(image, points_per_batch=128, pred_iou_thresh=0.88)
+```
+
+`masks` 는 다음과 같이 생겼습니다:
+
+```bash
+{'masks': [array([[False, False, False, ..., True, True, True],
+ [False, False, False, ..., True, True, True],
+ [False, False, False, ..., True, True, True],
+ ...,
+ [False, False, False, ..., False, False, False],
+ [False, False, False, ..., False, False, False],
+ [False, False, False, ..., False, False, False]]),
+ array([[False, False, False, ..., False, False, False],
+ [False, False, False, ..., False, False, False],
+ [False, False, False, ..., False, False, False],
+ ...,
+'scores': tensor([0.9972, 0.9917,
+ ...,
+}
+```
+
+위 내용을 아래와 같이 시각화할 수 있습니다:
+
+```python
+import matplotlib.pyplot as plt
+
+plt.imshow(image, cmap='gray')
+
+for i, mask in enumerate(masks["masks"]):
+ plt.imshow(mask, cmap='viridis', alpha=0.1, vmin=0, vmax=1)
+
+plt.axis('off')
+plt.show()
+```
+
+아래는 회색조 원본 이미지에 다채로운 색상의 맵을 겹쳐놓은 모습입니다. 매우 인상적인 결과입니다.
+
+
+
+
+
+## 모델 추론[[model-inference]]
+
+### 포인트 프롬프팅[[point-prompting]]
+
+파이프라인 없이도 모델을 사용할 수 있습니다. 이를 위해 모델과 프로세서를 초기화해야 합니다.
+
+```python
+from transformers import SamModel, SamProcessor
+import torch
+
+device = torch.device('cuda' if torch.cuda.is_available() else 'cpu')
+
+model = SamModel.from_pretrained("facebook/sam-vit-base").to(device)
+processor = SamProcessor.from_pretrained("facebook/sam-vit-base")
+```
+
+포인트 프롬프팅을 하기 위해, 입력 포인트를 프로세서에 전달한 다음, 프로세서 출력을 받아 모델에 전달하여 추론합니다. 모델 출력을 후처리하려면, 출력과 함께 프로세서의 초기 출력에서 가져온 `original_sizes`와 `reshaped_input_sizes`를 전달해야 합니다. 왜냐하면, 프로세서가 이미지 크기를 조정하고 출력을 추정해야 하기 때문입니다.
+
+```python
+input_points = [[[2592, 1728]]] # 벌의 포인트 위치
+
+inputs = processor(image, input_points=input_points, return_tensors="pt").to(device)
+with torch.no_grad():
+ outputs = model(**inputs)
+masks = processor.image_processor.post_process_masks(outputs.pred_masks.cpu(), inputs["original_sizes"].cpu(), inputs["reshaped_input_sizes"].cpu())
+```
+
+`masks` 출력으로 세 가지 마스크를 시각화할 수 있습니다.
+
+```python
+import matplotlib.pyplot as plt
+import numpy as np
+
+fig, axes = plt.subplots(1, 4, figsize=(15, 5))
+
+axes[0].imshow(image)
+axes[0].set_title('Original Image')
+mask_list = [masks[0][0][0].numpy(), masks[0][0][1].numpy(), masks[0][0][2].numpy()]
+
+for i, mask in enumerate(mask_list, start=1):
+ overlayed_image = np.array(image).copy()
+
+ overlayed_image[:,:,0] = np.where(mask == 1, 255, overlayed_image[:,:,0])
+ overlayed_image[:,:,1] = np.where(mask == 1, 0, overlayed_image[:,:,1])
+ overlayed_image[:,:,2] = np.where(mask == 1, 0, overlayed_image[:,:,2])
+
+ axes[i].imshow(overlayed_image)
+ axes[i].set_title(f'Mask {i}')
+for ax in axes:
+ ax.axis('off')
+
+plt.show()
+```
+
+
+
+
+
+### 박스 프롬프팅[[box-prompting]]
+
+박스 프롬프팅도 포인트 프롬프팅과 유사한 방식으로 할 수 있습니다. 입력 박스를 `[x_min, y_min, x_max, y_max]` 형식의 리스트로 작성하여 이미지와 함께 `processor`에 전달할 수 있습니다. 프로세서 출력을 받아 모델에 직접 전달한 후, 다시 출력을 후처리해야 합니다.
+
+```python
+# 벌 주위의 바운딩 박스
+box = [2350, 1600, 2850, 2100]
+
+inputs = processor(
+ image,
+ input_boxes=[[[box]]],
+ return_tensors="pt"
+ ).to("cuda")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+mask = processor.image_processor.post_process_masks(
+ outputs.pred_masks.cpu(),
+ inputs["original_sizes"].cpu(),
+ inputs["reshaped_input_sizes"].cpu()
+)[0][0][0].numpy()
+```
+
+이제 아래와 같이, 벌 주위의 바운딩 박스를 시각화할 수 있습니다.
+
+```python
+import matplotlib.patches as patches
+
+fig, ax = plt.subplots()
+ax.imshow(image)
+
+rectangle = patches.Rectangle((2350, 1600), 500, 500, linewidth=2, edgecolor='r', facecolor='none')
+ax.add_patch(rectangle)
+ax.axis("off")
+plt.show()
+```
+
+
+
+
+
+아래에서 추론 결과를 확인할 수 있습니다.
+
+```python
+fig, ax = plt.subplots()
+ax.imshow(image)
+ax.imshow(mask, cmap='viridis', alpha=0.4)
+
+ax.axis("off")
+plt.show()
+```
+
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/masked_language_modeling.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/masked_language_modeling.md
new file mode 100644
index 0000000000000000000000000000000000000000..74df085c5b558fcaecc6828076a7cd4e9b6601c8
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/masked_language_modeling.md
@@ -0,0 +1,441 @@
+
+
+# 마스킹된 언어 모델링(Masked language modeling)[[masked-language-modeling]]
+
+[[open-in-colab]]
+
+
+
+마스킹된 언어 모델링은 시퀀스에서 마스킹된 토큰을 예측하며, 모델은 양방향으로 토큰에 액세스할 수 있습니다.
+즉, 모델은 토큰의 왼쪽과 오른쪽 양쪽에서 접근할 수 있습니다.
+마스킹된 언어 모델링은 전체 시퀀스에 대한 문맥적 이해가 필요한 작업에 적합하며, BERT가 그 예에 해당합니다.
+
+이번 가이드에서 다룰 내용은 다음과 같습니다:
+
+1. [ELI5](https://huggingface.co/datasets/eli5) 데이터 세트에서 [r/askscience](https://www.reddit.com/r/askscience/) 부분을 사용해 [DistilRoBERTa](https://huggingface.co/distilbert/distilroberta-base) 모델을 미세 조정합니다.
+2. 추론 시에 직접 미세 조정한 모델을 사용합니다.
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/fill-mask)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+Hugging Face 계정에 로그인하여 모델을 업로드하고 커뮤니티와의 공유를 권장합니다. 메시지가 표시되면(When prompted) 토큰을 입력하여 로그인합니다:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## ELI5 데이터 세트 가져오기[[load-eli5-dataset]]
+
+먼저 🤗 Datasets 라이브러리에서 ELI5 데이터 세트의 r/askscience 중 일부만 가져옵니다.
+이렇게 하면 전체 데이터 세트 학습에 더 많은 시간을 할애하기 전에 모든 것이 작동하는지 실험하고 확인할 수 있습니다.
+
+```py
+>>> from datasets import load_dataset
+
+>>> eli5 = load_dataset("eli5", split="train_asks[:5000]")
+```
+
+데이터 세트의 `train_asks`를 [`~datasets.Dataset.train_test_split`] 메소드를 사용해 훈련 데이터와 테스트 데이터로 분할합니다:
+
+```py
+>>> eli5 = eli5.train_test_split(test_size=0.2)
+```
+
+그리고 아래 예시를 살펴보세요:
+
+```py
+>>> eli5["train"][0]
+{'answers': {'a_id': ['c3d1aib', 'c3d4lya'],
+ 'score': [6, 3],
+ 'text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
+ "Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"]},
+ 'answers_urls': {'url': []},
+ 'document': '',
+ 'q_id': 'nyxfp',
+ 'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
+ 'selftext_urls': {'url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg']},
+ 'subreddit': 'askscience',
+ 'title': 'Few questions about this space walk photograph.',
+ 'title_urls': {'url': []}}
+```
+
+많아 보일 수 있지만 실제로는 `text` 필드에만 집중하면 됩나다.
+언어 모델링 작업의 멋진 점은 (비지도 학습으로) *다음 단어가 레이블*이기 때문에 레이블이 따로 필요하지 않습니다.
+
+## 전처리[[preprocess]]
+
+
+
+마스킹된 언어 모델링을 위해, 다음 단계로 DistilRoBERTa 토크나이저를 가져와서 `text` 하위 필드를 처리합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilroberta-base")
+```
+
+위의 예제에서와 마찬가지로, `text` 필드는 `answers` 안에 중첩되어 있습니다.
+따라서 중첩된 구조에서 [`flatten`](https://huggingface.co/docs/datasets/process#flatten) 메소드를 사용하여 `text` 하위 필드를 추출합니다:
+
+```py
+>>> eli5 = eli5.flatten()
+>>> eli5["train"][0]
+{'answers.a_id': ['c3d1aib', 'c3d4lya'],
+ 'answers.score': [6, 3],
+ 'answers.text': ["The velocity needed to remain in orbit is equal to the square root of Newton's constant times the mass of earth divided by the distance from the center of the earth. I don't know the altitude of that specific mission, but they're usually around 300 km. That means he's going 7-8 km/s.\n\nIn space there are no other forces acting on either the shuttle or the guy, so they stay in the same position relative to each other. If he were to become unable to return to the ship, he would presumably run out of oxygen, or slowly fall into the atmosphere and burn up.",
+ "Hope you don't mind me asking another question, but why aren't there any stars visible in this photo?"],
+ 'answers_urls.url': [],
+ 'document': '',
+ 'q_id': 'nyxfp',
+ 'selftext': '_URL_0_\n\nThis was on the front page earlier and I have a few questions about it. Is it possible to calculate how fast the astronaut would be orbiting the earth? Also how does he stay close to the shuttle so that he can return safely, i.e is he orbiting at the same speed and can therefore stay next to it? And finally if his propulsion system failed, would he eventually re-enter the atmosphere and presumably die?',
+ 'selftext_urls.url': ['http://apod.nasa.gov/apod/image/1201/freeflyer_nasa_3000.jpg'],
+ 'subreddit': 'askscience',
+ 'title': 'Few questions about this space walk photograph.',
+ 'title_urls.url': []}
+```
+
+이제 각 하위 필드는 `answers` 접두사(prefix)로 표시된 대로 별도의 열이 되고, `text` 필드는 이제 리스트가 되었습니다.
+각 문장을 개별적으로 토큰화하는 대신 리스트를 문자열로 변환하여 한번에 토큰화할 수 있습니다.
+
+다음은 각 예제에 대해 문자열로 이루어진 리스트를 `join`하고 결과를 토큰화하는 첫 번째 전처리 함수입니다:
+
+```py
+>>> def preprocess_function(examples):
+... return tokenizer([" ".join(x) for x in examples["answers.text"]])
+```
+
+이 전처리 함수를 전체 데이터 세트에 적용하기 위해 🤗 Datasets [`~datasets.Dataset.map`] 메소드를 사용합니다.
+데이터 세트의 여러 요소를 한 번에 처리하도록 `batched=True`를 설정하고 `num_proc`로 처리 횟수를 늘리면 `map` 함수의 속도를 높일 수 있습니다.
+필요하지 않은 열은 제거합니다:
+
+```py
+>>> tokenized_eli5 = eli5.map(
+... preprocess_function,
+... batched=True,
+... num_proc=4,
+... remove_columns=eli5["train"].column_names,
+... )
+```
+
+이 데이터 세트에는 토큰 시퀀스가 포함되어 있지만 이 중 일부는 모델의 최대 입력 길이보다 깁니다.
+
+이제 두 번째 전처리 함수를 사용해
+- 모든 시퀀스를 연결하고
+- 연결된 시퀀스를 정의한 `block_size` 보다 더 짧은 덩어리로 분할하는데, 이 덩어리는 모델의 최대 입력 길이보다 짧고 GPU RAM이 수용할 수 있는 길이여야 합니다.
+
+
+```py
+>>> block_size = 128
+
+
+>>> def group_texts(examples):
+... # Concatenate all texts.
+... concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
+... total_length = len(concatenated_examples[list(examples.keys())[0]])
+... # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
+... # customize this part to your needs.
+... if total_length >= block_size:
+... total_length = (total_length // block_size) * block_size
+... # Split by chunks of block_size.
+... result = {
+... k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+... for k, t in concatenated_examples.items()
+... }
+... result["labels"] = result["input_ids"].copy()
+... return result
+```
+
+전체 데이터 세트에 `group_texts` 함수를 적용합니다:
+
+```py
+>>> lm_dataset = tokenized_eli5.map(group_texts, batched=True, num_proc=4)
+```
+
+이제 [`DataCollatorForLanguageModeling`]을 사용하여 데이터 예제의 배치를 생성합니다.
+데이터 세트 전체를 최대 길이로 패딩하는 것보다 collation 단계에서 매 배치안에서의 최대 길이로 문장을 *동적으로 패딩*하는 것이 더 효율적입니다.
+
+
+
+
+시퀀스 끝 토큰을 패딩 토큰으로 사용하고 데이터를 반복할 때마다 토큰을 무작위로 마스킹하도록 `mlm_-probability`를 지정합니다:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> tokenizer.pad_token = tokenizer.eos_token
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=0.15)
+```
+
+
+
+시퀀스 끝 토큰을 패딩 토큰으로 사용하고 데이터를 반복할 때마다 토큰을 무작위로 마스킹하도록 `mlm_-probability`를 지정합니다:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=0.15, return_tensors="tf")
+```
+
+
+
+## 훈련[[train]]
+
+
+
+
+
+[`Trainer`]로 모델을 미세 조정하는 데 익숙하지 않다면 기본 튜토리얼 [여기](../training#train-with-pytorch-trainer)를 살펴보세요!
+
+
+이제 모델 훈련을 시작할 준비가 되었습니다! [`AutoModelForMaskedLM`]를 사용해 DistilRoBERTa 모델을 가져옵니다:
+
+```py
+>>> from transformers import AutoModelForMaskedLM
+
+>>> model = AutoModelForMaskedLM.from_pretrained("distilbert/distilroberta-base")
+```
+
+이제 세 단계가 남았습니다:
+
+1. [`TrainingArguments`]의 훈련 하이퍼파라미터를 정의합니다. 모델 저장 위치를 지정하는 `output_dir`은 유일한 필수 파라미터입니다. `push_to_hub=True`를 설정하여 이 모델을 Hub에 업로드합니다 (모델을 업로드하려면 Hugging Face에 로그인해야 합니다).
+2. 모델, 데이터 세트 및 데이터 콜레이터(collator)와 함께 훈련 인수를 [`Trainer`]에 전달합니다.
+3. [`~Trainer.train`]을 호출하여 모델을 미세 조정합니다.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_eli5_mlm_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=lm_dataset["train"],
+... eval_dataset=lm_dataset["test"],
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면 [`~transformers.Trainer.evaluate`] 메소드를 사용하여 펄플렉서티(perplexity)를 계산하고 모델을 평가합니다:
+
+```py
+>>> import math
+
+>>> eval_results = trainer.evaluate()
+>>> print(f"Perplexity: {math.exp(eval_results['eval_loss']):.2f}")
+Perplexity: 8.76
+```
+
+그리고 [`~transformers.Trainer.push_to_hub`] 메소드를 사용해 다른 사람들이 사용할 수 있도록, Hub로 모델을 업로드합니다.
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras로 모델을 미세 조정하는 데 익숙하지 않다면 기본 튜토리얼 [여기](../training#train-a-tensorflow-model-with-keras)를 살펴보세요!
+
+
+TensorFlow로 모델을 미세 조정하기 위해서는 옵티마이저(optimizer) 함수 설정, 학습률(learning rate) 스케쥴링, 훈련 하이퍼파라미터 설정부터 시작하세요:
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+다음으로 [`TFAutoModelForMaskedLM`]를 사용해 DistilRoBERTa 모델을 가져옵니다:
+
+```py
+>>> from transformers import TFAutoModelForMaskedLM
+
+>>> model = TFAutoModelForMaskedLM.from_pretrained("distilbert/distilroberta-base")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`] 메소드를 사용해 데이터 세트를 `tf.data.Dataset` 형식으로 변환하세요:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... lm_dataset["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... lm_dataset["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method) 메소드를 통해 모델 훈련을 구성합니다:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+이는 업로드할 모델과 토크나이저의 위치를 [`~transformers.PushToHubCallback`]에 지정하여 수행할 수 있습니다:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_eli5_mlm_model",
+... tokenizer=tokenizer,
+... )
+```
+
+드디어 모델을 훈련할 준비가 되었습니다!
+모델을 미세 조정할 때 훈련 및 검증 데이터 세트, 에포크 수, 콜백이 포함된 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)을 호출합니다:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=[callback])
+```
+
+훈련이 완료되면, 자동으로 Hub로 업로드되어 누구나 사용할 수 있습니다!
+
+
+
+
+
+마스킹된 언어 모델링을 위해 모델을 미세 조정하는 방법에 대한 보다 심층적인 예제는
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)
+또는 [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb)을 참조하세요.
+
+
+## 추론[[inference]]
+
+지금까지 모델 미세 조정을 잘 했으니, 추론에 사용할 수 있습니다!
+
+모델이 빈칸을 채울 텍스트를 스페셜 토큰(special token)인 `` 토큰으로 표시합니다:
+
+
+```py
+>>> text = "The Milky Way is a galaxy."
+```
+추론을 위해 미세 조정한 모델을 테스트하는 가장 간단한 방법은 [`pipeline`]에서 사용하는 것입니다.
+`fill-mask`태스크로 `pipeline`을 인스턴스화하고 텍스트를 전달합니다.
+`top_k` 매개변수를 사용하여 반환하는 예측의 수를 지정할 수 있습니다:
+
+```py
+>>> from transformers import pipeline
+
+>>> mask_filler = pipeline("fill-mask", "stevhliu/my_awesome_eli5_mlm_model")
+>>> mask_filler(text, top_k=3)
+[{'score': 0.5150994658470154,
+ 'token': 21300,
+ 'token_str': ' spiral',
+ 'sequence': 'The Milky Way is a spiral galaxy.'},
+ {'score': 0.07087188959121704,
+ 'token': 2232,
+ 'token_str': ' massive',
+ 'sequence': 'The Milky Way is a massive galaxy.'},
+ {'score': 0.06434620916843414,
+ 'token': 650,
+ 'token_str': ' small',
+ 'sequence': 'The Milky Way is a small galaxy.'}]
+```
+
+
+
+텍스트를 토큰화하고 `input_ids`를 PyTorch 텐서 형태로 반환합니다.
+또한, `` 토큰의 위치를 지정해야 합니다:
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_mlm_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+>>> mask_token_index = torch.where(inputs["input_ids"] == tokenizer.mask_token_id)[1]
+```
+
+모델에 `inputs`를 입력하고, 마스킹된 토큰의 `logits`를 반환합니다:
+
+```py
+>>> from transformers import AutoModelForMaskedLM
+
+>>> model = AutoModelForMaskedLM.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
+>>> logits = model(**inputs).logits
+>>> mask_token_logits = logits[0, mask_token_index, :]
+```
+
+그런 다음 가장 높은 확률은 가진 마스크 토큰 3개를 반환하고, 출력합니다:
+```py
+>>> top_3_tokens = torch.topk(mask_token_logits, 3, dim=1).indices[0].tolist()
+
+>>> for token in top_3_tokens:
+... print(text.replace(tokenizer.mask_token, tokenizer.decode([token])))
+The Milky Way is a spiral galaxy.
+The Milky Way is a massive galaxy.
+The Milky Way is a small galaxy.
+```
+
+
+텍스트를 토큰화하고 `input_ids`를 TensorFlow 텐서 형태로 반환합니다.
+또한, `` 토큰의 위치를 지정해야 합니다:
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_eli5_mlm_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+>>> mask_token_index = tf.where(inputs["input_ids"] == tokenizer.mask_token_id)[0, 1]
+```
+
+모델에 `inputs`를 입력하고, 마스킹된 토큰의 `logits`를 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForMaskedLM
+
+>>> model = TFAutoModelForMaskedLM.from_pretrained("stevhliu/my_awesome_eli5_mlm_model")
+>>> logits = model(**inputs).logits
+>>> mask_token_logits = logits[0, mask_token_index, :]
+```
+
+그런 다음 가장 높은 확률은 가진 마스크 토큰 3개를 반환하고, 출력합니다:
+```py
+>>> top_3_tokens = tf.math.top_k(mask_token_logits, 3).indices.numpy()
+
+>>> for token in top_3_tokens:
+... print(text.replace(tokenizer.mask_token, tokenizer.decode([token])))
+The Milky Way is a spiral galaxy.
+The Milky Way is a massive galaxy.
+The Milky Way is a small galaxy.
+```
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/monocular_depth_estimation.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/monocular_depth_estimation.md
new file mode 100644
index 0000000000000000000000000000000000000000..2c640d2a86db3d59e63111be73a314313e7aee08
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/monocular_depth_estimation.md
@@ -0,0 +1,144 @@
+
+
+# 단일 영상 기반 깊이 추정[[depth-estimation-pipeline]]
+
+단일 영상 기반 깊이 추정은 한 장면의 단일 이미지에서 장면의 깊이 정보를 예측하는 컴퓨터 비전 작업입니다.
+즉, 단일 카메라 시점의 장면에 있는 물체의 거리를 예측하는 과정입니다.
+
+단일 영상 기반 깊이 추정은 3D 재구성, 증강 현실, 자율 주행, 로봇 공학 등 다양한 분야에서 응용됩니다.
+조명 조건, 가려짐, 텍스처와 같은 요소의 영향을 받을 수 있는 장면 내 물체와 해당 깊이 정보 간의 복잡한 관계를 모델이 이해해야 하므로 까다로운 작업입니다.
+
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/depth-estimation)를 확인하는 것이 좋습니다.
+
+
+
+이번 가이드에서 배울 내용은 다음과 같습니다:
+
+* 깊이 추정 파이프라인 만들기
+* 직접 깊이 추정 추론하기
+
+시작하기 전에, 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install -q transformers
+```
+
+## 깊이 추정 파이프라인[[depth-estimation-inference-by-hand]]
+
+깊이 추정을 추론하는 가장 간단한 방법은 해당 기능을 제공하는 [`pipeline`]을 사용하는 것입니다.
+[Hugging Face Hub 체크포인트](https://huggingface.co/models?pipeline_tag=depth-estimation&sort=downloads)에서 파이프라인을 초기화합니다:
+
+```py
+>>> from transformers import pipeline
+
+>>> checkpoint = "vinvino02/glpn-nyu"
+>>> depth_estimator = pipeline("depth-estimation", model=checkpoint)
+```
+
+
+다음으로, 분석할 이미지를 한 장 선택하세요:
+
+```py
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "https://unsplash.com/photos/HwBAsSbPBDU/download?ixid=MnwxMjA3fDB8MXxzZWFyY2h8MzR8fGNhciUyMGluJTIwdGhlJTIwc3RyZWV0fGVufDB8MHx8fDE2Nzg5MDEwODg&force=true&w=640"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> image
+```
+
+
+
+
+
+이미지를 파이프라인으로 전달합니다.
+
+```py
+>>> predictions = depth_estimator(image)
+```
+
+파이프라인은 두 개의 항목을 가지는 딕셔너리를 반환합니다.
+첫 번째는 `predicted_depth`로 각 픽셀의 깊이를 미터로 표현한 값을 가지는 텐서입니다.
+두 번째는 `depth`로 깊이 추정 결과를 시각화하는 PIL 이미지입니다.
+
+이제 시각화한 결과를 살펴보겠습니다:
+
+```py
+>>> predictions["depth"]
+```
+
+
+
+
+
+## 직접 깊이 추정 추론하기[[depth-estimation-inference-by-hand]]
+
+이제 깊이 추정 파이프라인 사용법을 살펴보았으니 동일한 결과를 복제하는 방법을 살펴보겠습니다.
+[Hugging Face Hub 체크포인트](https://huggingface.co/models?pipeline_tag=depth-estimation&sort=downloads)에서 모델과 관련 프로세서를 가져오는 것부터 시작합니다.
+여기서 이전에 사용한 체크포인트와 동일한 것을 사용합니다:
+
+```py
+>>> from transformers import AutoImageProcessor, AutoModelForDepthEstimation
+
+>>> checkpoint = "vinvino02/glpn-nyu"
+
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
+>>> model = AutoModelForDepthEstimation.from_pretrained(checkpoint)
+```
+
+필요한 이미지 변환을 처리하는 `image_processor`를 사용하여 모델에 대한 이미지 입력을 준비합니다.
+`image_processor`는 크기 조정 및 정규화 등 필요한 이미지 변환을 처리합니다:
+
+```py
+>>> pixel_values = image_processor(image, return_tensors="pt").pixel_values
+```
+
+준비한 입력을 모델로 전달합니다:
+
+```py
+>>> import torch
+
+>>> with torch.no_grad():
+... outputs = model(pixel_values)
+... predicted_depth = outputs.predicted_depth
+```
+
+결과를 시각화합니다:
+
+```py
+>>> import numpy as np
+
+>>> # 원본 사이즈로 복원
+>>> prediction = torch.nn.functional.interpolate(
+... predicted_depth.unsqueeze(1),
+... size=image.size[::-1],
+... mode="bicubic",
+... align_corners=False,
+... ).squeeze()
+>>> output = prediction.numpy()
+
+>>> formatted = (output * 255 / np.max(output)).astype("uint8")
+>>> depth = Image.fromarray(formatted)
+>>> depth
+```
+
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/multiple_choice.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/multiple_choice.md
new file mode 100644
index 0000000000000000000000000000000000000000..e0888f4a0b6de15fdd7afafea07194a91ce67424
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/multiple_choice.md
@@ -0,0 +1,369 @@
+
+
+# 객관식 문제[[multiple-choice]]
+
+[[open-in-colab]]
+
+객관식 과제는 문맥과 함께 여러 개의 후보 답변이 제공되고 모델이 정답을 선택하도록 학습된다는 점을 제외하면 질의응답과 유사합니다.
+
+진행하는 방법은 아래와 같습니다:
+
+1. [SWAG](https://huggingface.co/datasets/swag) 데이터 세트의 'regular' 구성으로 [BERT](https://huggingface.co/google-bert/bert-base-uncased)를 미세 조정하여 여러 옵션과 일부 컨텍스트가 주어졌을 때 가장 적합한 답을 선택합니다.
+2. 추론에 미세 조정된 모델을 사용합니다.
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+모델을 업로드하고 커뮤니티와 공유할 수 있도록 허깅페이스 계정에 로그인하는 것이 좋습니다. 메시지가 표시되면 토큰을 입력하여 로그인합니다:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## SWAG 데이터 세트 가져오기[[load-swag-dataset]]
+
+먼저 🤗 Datasets 라이브러리에서 SWAG 데이터셋의 '일반' 구성을 가져옵니다:
+
+```py
+>>> from datasets import load_dataset
+
+>>> swag = load_dataset("swag", "regular")
+```
+
+이제 데이터를 살펴봅니다:
+
+```py
+>>> swag["train"][0]
+{'ending0': 'passes by walking down the street playing their instruments.',
+ 'ending1': 'has heard approaching them.',
+ 'ending2': "arrives and they're outside dancing and asleep.",
+ 'ending3': 'turns the lead singer watches the performance.',
+ 'fold-ind': '3416',
+ 'gold-source': 'gold',
+ 'label': 0,
+ 'sent1': 'Members of the procession walk down the street holding small horn brass instruments.',
+ 'sent2': 'A drum line',
+ 'startphrase': 'Members of the procession walk down the street holding small horn brass instruments. A drum line',
+ 'video-id': 'anetv_jkn6uvmqwh4'}
+```
+
+여기에는 많은 필드가 있는 것처럼 보이지만 실제로는 매우 간단합니다:
+
+- `sent1` 및 `sent2`: 이 필드는 문장이 어떻게 시작되는지 보여주며, 이 두 필드를 합치면 `시작 구절(startphrase)` 필드가 됩니다.
+- `종료 구절(ending)`: 문장이 어떻게 끝날 수 있는지에 대한 가능한 종료 구절를 제시하지만 그 중 하나만 정답입니다.
+- `레이블(label)`: 올바른 문장 종료 구절을 식별합니다.
+
+## 전처리[[preprocess]]
+
+다음 단계는 문장의 시작과 네 가지 가능한 구절을 처리하기 위해 BERT 토크나이저를 불러옵니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+```
+
+생성하려는 전처리 함수는 다음과 같아야 합니다:
+
+1. `sent1` 필드를 네 개 복사한 다음 각각을 `sent2`와 결합하여 문장이 시작되는 방식을 재현합니다.
+2. `sent2`를 네 가지 가능한 문장 구절 각각과 결합합니다.
+3. 이 두 목록을 토큰화할 수 있도록 평탄화(flatten)하고, 각 예제에 해당하는 `input_ids`, `attention_mask` 및 `labels` 필드를 갖도록 다차원화(unflatten) 합니다.
+
+```py
+>>> ending_names = ["ending0", "ending1", "ending2", "ending3"]
+
+
+>>> def preprocess_function(examples):
+... first_sentences = [[context] * 4 for context in examples["sent1"]]
+... question_headers = examples["sent2"]
+... second_sentences = [
+... [f"{header} {examples[end][i]}" for end in ending_names] for i, header in enumerate(question_headers)
+... ]
+
+... first_sentences = sum(first_sentences, [])
+... second_sentences = sum(second_sentences, [])
+
+... tokenized_examples = tokenizer(first_sentences, second_sentences, truncation=True)
+... return {k: [v[i : i + 4] for i in range(0, len(v), 4)] for k, v in tokenized_examples.items()}
+```
+
+전체 데이터 집합에 전처리 기능을 적용하려면 🤗 Datasets [`~datasets.Dataset.map`] 메소드를 사용합니다. `batched=True`를 설정하여 데이터 집합의 여러 요소를 한 번에 처리하면 `map` 함수의 속도를 높일 수 있습니다:
+
+```py
+tokenized_swag = swag.map(preprocess_function, batched=True)
+```
+
+[`DataCollatorForMultipleChoice`]는 모든 모델 입력을 평탄화하고 패딩을 적용하며 그 결과를 결과를 다차원화합니다:
+```py
+>>> from transformers import DataCollatorForMultipleChoice
+>>> collator = DataCollatorForMultipleChoice(tokenizer=tokenizer)
+```
+
+## 평가 하기[[evaluate]]
+
+훈련 중에 메트릭을 포함하면 모델의 성능을 평가하는 데 도움이 되는 경우가 많습니다. 🤗[Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하여 평가 방법을 빠르게 가져올 수 있습니다. 이 작업에서는 [accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) 지표를 가져옵니다(🤗 Evaluate [둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하여 지표를 가져오고 계산하는 방법에 대해 자세히 알아보세요):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+그리고 예측과 레이블을 [`~evaluate.EvaluationModule.compute`]에 전달하여 정확도를 계산하는 함수를 만듭니다:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... predictions = np.argmax(predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=labels)
+```
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었으며, 훈련을 설정할 때 이 함수로 돌아가게 됩니다.
+
+## 훈련 하기[[train]]
+
+
+
+
+
+[`Trainer`]로 모델을 미세 조정하는 데 익숙하지 않다면 기본 튜토리얼 [여기](../training#train-with-pytorch-trainer)를 살펴보세요!
+
+
+
+이제 모델 훈련을 시작할 준비가 되었습니다! [`AutoModelForMultipleChoice`]로 BERT를 로드합니다:
+
+```py
+>>> from transformers import AutoModelForMultipleChoice, TrainingArguments, Trainer
+
+>>> model = AutoModelForMultipleChoice.from_pretrained("google-bert/bert-base-uncased")
+```
+
+이제 세 단계만 남았습니다:
+
+1. 훈련 하이퍼파라미터를 [`TrainingArguments`]에 정의합니다. 유일한 필수 매개변수는 모델을 저장할 위치를 지정하는 `output_dir`입니다. `push_to_hub=True`를 설정하여 이 모델을 허브에 푸시합니다(모델을 업로드하려면 허깅 페이스에 로그인해야 합니다). 각 에폭이 끝날 때마다 [`Trainer`]가 정확도를 평가하고 훈련 체크포인트를 저장합니다.
+2. 모델, 데이터 세트, 토크나이저, 데이터 콜레이터, `compute_metrics` 함수와 함께 훈련 인자를 [`Trainer`]에 전달합니다.
+3. [`~Trainer.train`]을 사용하여 모델을 미세 조정합니다.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_swag_model",
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... load_best_model_at_end=True,
+... learning_rate=5e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_swag["train"],
+... eval_dataset=tokenized_swag["validation"],
+... processing_class=tokenizer,
+... data_collator=collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면 모든 사람이 모델을 사용할 수 있도록 [`~transformers.Trainer.push_to_hub`] 메소드를 사용하여 모델을 허브에 공유하세요:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras로 모델을 미세 조정하는 데 익숙하지 않다면 기본 튜토리얼 [여기](../training#train-a-tensorflow-model-with-keras)를 살펴보시기 바랍니다!
+
+
+TensorFlow에서 모델을 미세 조정하려면 최적화 함수, 학습률 스케쥴 및 몇 가지 학습 하이퍼파라미터를 설정하는 것부터 시작하세요:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_train_epochs = 2
+>>> total_train_steps = (len(tokenized_swag["train"]) // batch_size) * num_train_epochs
+>>> optimizer, schedule = create_optimizer(init_lr=5e-5, num_warmup_steps=0, num_train_steps=total_train_steps)
+```
+
+그리고 [`TFAutoModelForMultipleChoice`]로 BERT를 가져올 수 있습니다:
+
+```py
+>>> from transformers import TFAutoModelForMultipleChoice
+
+>>> model = TFAutoModelForMultipleChoice.from_pretrained("google-bert/bert-base-uncased")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]을 사용하여 데이터 세트를 `tf.data.Dataset` 형식으로 변환합니다:
+
+```py
+>>> data_collator = DataCollatorForMultipleChoice(tokenizer=tokenizer)
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_swag["train"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_swag["validation"],
+... shuffle=False,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)을 사용하여 훈련 모델을 구성합니다:
+
+```py
+>>> model.compile(optimizer=optimizer)
+```
+
+훈련을 시작하기 전에 설정해야 할 마지막 두 가지는 예측의 정확도를 계산하고 모델을 허브로 푸시하는 방법을 제공하는 것입니다. 이 두 가지 작업은 모두 [Keras 콜백](../main_classes/keras_callbacks)을 사용하여 수행할 수 있습니다.
+
+`compute_metrics`함수를 [`~transformers.KerasMetricCallback`]에 전달하세요:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+모델과 토크나이저를 업로드할 위치를 [`~transformers.PushToHubCallback`]에서 지정하세요:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_model",
+... tokenizer=tokenizer,
+... )
+```
+
+그리고 콜백을 함께 묶습니다:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+이제 모델 훈련을 시작합니다! 훈련 및 검증 데이터 세트, 에폭 수, 콜백을 사용하여 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)을 호출하고 모델을 미세 조정합니다:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=2, callbacks=callbacks)
+```
+
+훈련이 완료되면 모델이 자동으로 허브에 업로드되어 누구나 사용할 수 있습니다!
+
+
+
+
+
+
+객관식 모델을 미세 조정하는 방법에 대한 보다 심층적인 예는 아래 문서를 참조하세요.
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice.ipynb)
+또는 [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice-tf.ipynb).
+
+
+
+## 추론 하기[[inference]]
+
+이제 모델을 미세 조정했으니 추론에 사용할 수 있습니다!
+
+텍스트와 두 개의 후보 답안을 작성합니다:
+
+```py
+>>> prompt = "France has a bread law, Le Décret Pain, with strict rules on what is allowed in a traditional baguette."
+>>> candidate1 = "The law does not apply to croissants and brioche."
+>>> candidate2 = "The law applies to baguettes."
+```
+
+
+
+각 프롬프트와 후보 답변 쌍을 토큰화하여 PyTorch 텐서를 반환합니다. 또한 `labels`을 생성해야 합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_swag_model")
+>>> inputs = tokenizer([[prompt, candidate1], [prompt, candidate2]], return_tensors="pt", padding=True)
+>>> labels = torch.tensor(0).unsqueeze(0)
+```
+
+입력과 레이블을 모델에 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import AutoModelForMultipleChoice
+
+>>> model = AutoModelForMultipleChoice.from_pretrained("my_awesome_swag_model")
+>>> outputs = model(**{k: v.unsqueeze(0) for k, v in inputs.items()}, labels=labels)
+>>> logits = outputs.logits
+```
+
+가장 높은 확률을 가진 클래스를 가져옵니다:
+
+```py
+>>> predicted_class = logits.argmax().item()
+>>> predicted_class
+'0'
+```
+
+
+각 프롬프트와 후보 답안 쌍을 토큰화하여 텐서플로 텐서를 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_swag_model")
+>>> inputs = tokenizer([[prompt, candidate1], [prompt, candidate2]], return_tensors="tf", padding=True)
+```
+
+모델에 입력을 전달하고 `logits`를 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForMultipleChoice
+
+>>> model = TFAutoModelForMultipleChoice.from_pretrained("my_awesome_swag_model")
+>>> inputs = {k: tf.expand_dims(v, 0) for k, v in inputs.items()}
+>>> outputs = model(inputs)
+>>> logits = outputs.logits
+```
+
+가장 높은 확률을 가진 클래스를 가져옵니다:
+
+```py
+>>> predicted_class = int(tf.math.argmax(logits, axis=-1)[0])
+>>> predicted_class
+'0'
+```
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/object_detection.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/object_detection.md
new file mode 100644
index 0000000000000000000000000000000000000000..e027ad65a9ada8c07b0af7403cf62d1e31f37099
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/object_detection.md
@@ -0,0 +1,583 @@
+
+
+# 객체 탐지 [[object-detection]]
+
+[[open-in-colab]]
+
+객체 탐지는 이미지에서 인스턴스(예: 사람, 건물 또는 자동차)를 감지하는 컴퓨터 비전 작업입니다. 객체 탐지 모델은 이미지를 입력으로 받고 탐지된 바운딩 박스의 좌표와 관련된 레이블을 출력합니다.
+하나의 이미지에는 여러 객체가 있을 수 있으며 각각은 자체적인 바운딩 박스와 레이블을 가질 수 있습니다(예: 차와 건물이 있는 이미지).
+또한 각 객체는 이미지의 다른 부분에 존재할 수 있습니다(예: 이미지에 여러 대의 차가 있을 수 있음).
+이 작업은 보행자, 도로 표지판, 신호등과 같은 것들을 감지하는 자율 주행에 일반적으로 사용됩니다.
+다른 응용 분야로는 이미지 내 객체 수 계산 및 이미지 검색 등이 있습니다.
+
+이 가이드에서 다음을 배울 것입니다:
+
+ 1. 합성곱 백본(인풋 데이터의 특성을 추출하는 합성곱 네트워크)과 인코더-디코더 트랜스포머 모델을 결합한 [DETR](https://huggingface.co/docs/transformers/model_doc/detr) 모델을 [CPPE-5](https://huggingface.co/datasets/cppe-5) 데이터 세트에 대해 미세조정 하기
+ 2. 미세조정 한 모델을 추론에 사용하기.
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/object-detection)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+```bash
+pip install -q datasets transformers evaluate timm albumentations
+```
+
+허깅페이스 허브에서 데이터 세트를 가져오기 위한 🤗 Datasets과 모델을 학습하기 위한 🤗 Transformers, 데이터를 증강하기 위한 `albumentations`를 사용합니다.
+DETR 모델의 합성곱 백본을 가져오기 위해서는 현재 `timm`이 필요합니다.
+
+커뮤니티에 모델을 업로드하고 공유할 수 있도록 Hugging Face 계정에 로그인하는 것을 권장합니다. 프롬프트가 나타나면 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## CPPE-5 데이터 세트 가져오기 [[load-the-CPPE-5-dataset]]
+
+[CPPE-5](https://huggingface.co/datasets/cppe-5) 데이터 세트는 COVID-19 대유행 상황에서 의료 전문인력 보호 장비(PPE)를 식별하는 어노테이션이 포함된 이미지를 담고 있습니다.
+
+데이터 세트를 가져오세요:
+
+```py
+>>> from datasets import load_dataset
+
+>>> cppe5 = load_dataset("cppe-5")
+>>> cppe5
+DatasetDict({
+ train: Dataset({
+ features: ['image_id', 'image', 'width', 'height', 'objects'],
+ num_rows: 1000
+ })
+ test: Dataset({
+ features: ['image_id', 'image', 'width', 'height', 'objects'],
+ num_rows: 29
+ })
+})
+```
+
+이 데이터 세트는 학습 세트 이미지 1,000개와 테스트 세트 이미지 29개를 갖고 있습니다.
+
+데이터에 익숙해지기 위해, 예시가 어떻게 구성되어 있는지 살펴보세요.
+
+```py
+>>> cppe5["train"][0]
+{'image_id': 15,
+ 'image': ,
+ 'width': 943,
+ 'height': 663,
+ 'objects': {'id': [114, 115, 116, 117],
+ 'area': [3796, 1596, 152768, 81002],
+ 'bbox': [[302.0, 109.0, 73.0, 52.0],
+ [810.0, 100.0, 57.0, 28.0],
+ [160.0, 31.0, 248.0, 616.0],
+ [741.0, 68.0, 202.0, 401.0]],
+ 'category': [4, 4, 0, 0]}}
+```
+
+데이터 세트에 있는 예시는 다음의 영역을 가지고 있습니다:
+
+- `image_id`: 예시 이미지 id
+- `image`: 이미지를 포함하는 `PIL.Image.Image` 객체
+- `width`: 이미지의 너비
+- `height`: 이미지의 높이
+- `objects`: 이미지 안의 객체들의 바운딩 박스 메타데이터를 포함하는 딕셔너리:
+ - `id`: 어노테이션 id
+ - `area`: 바운딩 박스의 면적
+ - `bbox`: 객체의 바운딩 박스 ([COCO 포맷](https://albumentations.ai/docs/getting_started/bounding_boxes_augmentation/#coco)으로)
+ - `category`: 객체의 카테고리, 가능한 값으로는 `Coverall (0)`, `Face_Shield (1)`, `Gloves (2)`, `Goggles (3)` 및 `Mask (4)` 가 포함됩니다.
+
+`bbox` 필드가 DETR 모델이 요구하는 COCO 형식을 따른다는 것을 알 수 있습니다.
+그러나 `objects` 내부의 필드 그룹은 DETR이 요구하는 어노테이션 형식과 다릅니다. 따라서 이 데이터를 학습에 사용하기 전에 전처리를 적용해야 합니다.
+
+데이터를 더 잘 이해하기 위해서 데이터 세트에서 한 가지 예시를 시각화하세요.
+
+```py
+>>> import numpy as np
+>>> import os
+>>> from PIL import Image, ImageDraw
+
+>>> image = cppe5["train"][0]["image"]
+>>> annotations = cppe5["train"][0]["objects"]
+>>> draw = ImageDraw.Draw(image)
+
+>>> categories = cppe5["train"].features["objects"].feature["category"].names
+
+>>> id2label = {index: x for index, x in enumerate(categories, start=0)}
+>>> label2id = {v: k for k, v in id2label.items()}
+
+>>> for i in range(len(annotations["id"])):
+... box = annotations["bbox"][i - 1]
+... class_idx = annotations["category"][i - 1]
+... x, y, w, h = tuple(box)
+... draw.rectangle((x, y, x + w, y + h), outline="red", width=1)
+... draw.text((x, y), id2label[class_idx], fill="white")
+
+>>> image
+```
+
+
+
+
+
+바운딩 박스와 연결된 레이블을 시각화하려면 데이터 세트의 메타 데이터, 특히 `category` 필드에서 레이블을 가져와야 합니다.
+또한 레이블 ID를 레이블 클래스에 매핑하는 `id2label`과 반대로 매핑하는 `label2id` 딕셔너리를 만들어야 합니다.
+모델을 설정할 때 이러한 매핑을 사용할 수 있습니다. 이러한 매핑은 허깅페이스 허브에서 모델을 공유했을 때 다른 사람들이 재사용할 수 있습니다.
+
+데이터를 더 잘 이해하기 위한 최종 단계로, 잠재적인 문제를 찾아보세요.
+객체 감지를 위한 데이터 세트에서 자주 발생하는 문제 중 하나는 바운딩 박스가 이미지의 가장자리를 넘어가는 것입니다.
+이러한 바운딩 박스를 "넘어가는 것(run away)"은 훈련 중에 오류를 발생시킬 수 있기에 이 단계에서 처리해야 합니다.
+이 데이터 세트에도 같은 문제가 있는 몇 가지 예가 있습니다. 이 가이드에서는 간단하게하기 위해 데이터에서 이러한 이미지를 제거합니다.
+
+```py
+>>> remove_idx = [590, 821, 822, 875, 876, 878, 879]
+>>> keep = [i for i in range(len(cppe5["train"])) if i not in remove_idx]
+>>> cppe5["train"] = cppe5["train"].select(keep)
+```
+
+## 데이터 전처리하기 [[preprocess-the-data]]
+
+모델을 미세 조정 하려면, 미리 학습된 모델에서 사용한 전처리 방식과 정확하게 일치하도록 사용할 데이터를 전처리해야 합니다.
+[`AutoImageProcessor`]는 이미지 데이터를 처리하여 DETR 모델이 학습에 사용할 수 있는 `pixel_values`, `pixel_mask`, 그리고 `labels`를 생성하는 작업을 담당합니다.
+이 이미지 프로세서에는 걱정하지 않아도 되는 몇 가지 속성이 있습니다:
+
+- `image_mean = [0.485, 0.456, 0.406 ]`
+- `image_std = [0.229, 0.224, 0.225]`
+
+
+이 값들은 모델 사전 훈련 중 이미지를 정규화하는 데 사용되는 평균과 표준 편차입니다.
+이 값들은 추론 또는 사전 훈련된 이미지 모델을 세밀하게 조정할 때 복제해야 하는 중요한 값입니다.
+
+사전 훈련된 모델과 동일한 체크포인트에서 이미지 프로세서를 인스턴스화합니다.
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> checkpoint = "facebook/detr-resnet-50"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
+```
+
+`image_processor`에 이미지를 전달하기 전에, 데이터 세트에 두 가지 전처리를 적용해야 합니다:
+
+- 이미지 증강
+- DETR 모델의 요구에 맞게 어노테이션을 다시 포맷팅
+
+첫째로, 모델이 학습 데이터에 과적합 되지 않도록 데이터 증강 라이브러리 중 아무거나 사용하여 변환을 적용할 수 있습니다. 여기에서는 [Albumentations](https://albumentations.ai/docs/) 라이브러리를 사용합니다...
+이 라이브러리는 변환을 이미지에 적용하고 바운딩 박스를 적절하게 업데이트하도록 보장합니다.
+🤗 Datasets 라이브러리 문서에는 [객체 탐지를 위해 이미지를 보강하는 방법에 대한 자세한 가이드](https://huggingface.co/docs/datasets/object_detection)가 있으며,
+이 예제와 정확히 동일한 데이터 세트를 사용합니다. 여기서는 각 이미지를 (480, 480) 크기로 조정하고, 좌우로 뒤집고, 밝기를 높이는 동일한 접근법을 적용합니다:
+
+
+```py
+>>> import albumentations
+>>> import numpy as np
+>>> import torch
+
+>>> transform = albumentations.Compose(
+... [
+... albumentations.Resize(480, 480),
+... albumentations.HorizontalFlip(p=1.0),
+... albumentations.RandomBrightnessContrast(p=1.0),
+... ],
+... bbox_params=albumentations.BboxParams(format="coco", label_fields=["category"]),
+... )
+```
+
+이미지 프로세서는 어노테이션이 다음과 같은 형식일 것으로 예상합니다: `{'image_id': int, 'annotations': List[Dict]}`, 여기서 각 딕셔너리는 COCO 객체 어노테이션입니다. 단일 예제에 대해 어노테이션의 형식을 다시 지정하는 함수를 추가해 보겠습니다:
+
+```py
+>>> def formatted_anns(image_id, category, area, bbox):
+... annotations = []
+... for i in range(0, len(category)):
+... new_ann = {
+... "image_id": image_id,
+... "category_id": category[i],
+... "isCrowd": 0,
+... "area": area[i],
+... "bbox": list(bbox[i]),
+... }
+... annotations.append(new_ann)
+
+... return annotations
+```
+
+이제 이미지와 어노테이션 전처리 변환을 결합하여 예제 배치에 사용할 수 있습니다:
+
+```py
+>>> # transforming a batch
+>>> def transform_aug_ann(examples):
+... image_ids = examples["image_id"]
+... images, bboxes, area, categories = [], [], [], []
+... for image, objects in zip(examples["image"], examples["objects"]):
+... image = np.array(image.convert("RGB"))[:, :, ::-1]
+... out = transform(image=image, bboxes=objects["bbox"], category=objects["category"])
+
+... area.append(objects["area"])
+... images.append(out["image"])
+... bboxes.append(out["bboxes"])
+... categories.append(out["category"])
+
+... targets = [
+... {"image_id": id_, "annotations": formatted_anns(id_, cat_, ar_, box_)}
+... for id_, cat_, ar_, box_ in zip(image_ids, categories, area, bboxes)
+... ]
+
+... return image_processor(images=images, annotations=targets, return_tensors="pt")
+```
+
+이전 단계에서 만든 전처리 함수를 🤗 Datasets의 [`~datasets.Dataset.with_transform`] 메소드를 사용하여 데이터 세트 전체에 적용합니다.
+이 메소드는 데이터 세트의 요소를 가져올 때마다 전처리 함수를 적용합니다.
+
+이 시점에서는 전처리 후 데이터 세트에서 예시 하나를 가져와서 변환 후 모양이 어떻게 되는지 확인해 볼 수 있습니다.
+이때, `pixel_values` 텐서, `pixel_mask` 텐서, 그리고 `labels`로 구성된 텐서가 있어야 합니다.
+
+```py
+>>> cppe5["train"] = cppe5["train"].with_transform(transform_aug_ann)
+>>> cppe5["train"][15]
+{'pixel_values': tensor([[[ 0.9132, 0.9132, 0.9132, ..., -1.9809, -1.9809, -1.9809],
+ [ 0.9132, 0.9132, 0.9132, ..., -1.9809, -1.9809, -1.9809],
+ [ 0.9132, 0.9132, 0.9132, ..., -1.9638, -1.9638, -1.9638],
+ ...,
+ [-1.5699, -1.5699, -1.5699, ..., -1.9980, -1.9980, -1.9980],
+ [-1.5528, -1.5528, -1.5528, ..., -1.9980, -1.9809, -1.9809],
+ [-1.5528, -1.5528, -1.5528, ..., -1.9980, -1.9809, -1.9809]],
+
+ [[ 1.3081, 1.3081, 1.3081, ..., -1.8431, -1.8431, -1.8431],
+ [ 1.3081, 1.3081, 1.3081, ..., -1.8431, -1.8431, -1.8431],
+ [ 1.3081, 1.3081, 1.3081, ..., -1.8256, -1.8256, -1.8256],
+ ...,
+ [-1.3179, -1.3179, -1.3179, ..., -1.8606, -1.8606, -1.8606],
+ [-1.3004, -1.3004, -1.3004, ..., -1.8606, -1.8431, -1.8431],
+ [-1.3004, -1.3004, -1.3004, ..., -1.8606, -1.8431, -1.8431]],
+
+ [[ 1.4200, 1.4200, 1.4200, ..., -1.6476, -1.6476, -1.6476],
+ [ 1.4200, 1.4200, 1.4200, ..., -1.6476, -1.6476, -1.6476],
+ [ 1.4200, 1.4200, 1.4200, ..., -1.6302, -1.6302, -1.6302],
+ ...,
+ [-1.0201, -1.0201, -1.0201, ..., -1.5604, -1.5604, -1.5604],
+ [-1.0027, -1.0027, -1.0027, ..., -1.5604, -1.5430, -1.5430],
+ [-1.0027, -1.0027, -1.0027, ..., -1.5604, -1.5430, -1.5430]]]),
+ 'pixel_mask': tensor([[1, 1, 1, ..., 1, 1, 1],
+ [1, 1, 1, ..., 1, 1, 1],
+ [1, 1, 1, ..., 1, 1, 1],
+ ...,
+ [1, 1, 1, ..., 1, 1, 1],
+ [1, 1, 1, ..., 1, 1, 1],
+ [1, 1, 1, ..., 1, 1, 1]]),
+ 'labels': {'size': tensor([800, 800]), 'image_id': tensor([756]), 'class_labels': tensor([4]), 'boxes': tensor([[0.7340, 0.6986, 0.3414, 0.5944]]), 'area': tensor([519544.4375]), 'iscrowd': tensor([0]), 'orig_size': tensor([480, 480])}}
+```
+
+각각의 이미지를 성공적으로 증강하고 이미지의 어노테이션을 준비했습니다.
+그러나 전처리는 아직 끝나지 않았습니다. 마지막 단계로, 이미지를 배치로 만들 사용자 정의 `collate_fn`을 생성합니다.
+해당 배치에서 가장 큰 이미지에 이미지(현재 `pixel_values` 인)를 패드하고, 실제 픽셀(1)과 패딩(0)을 나타내기 위해 그에 해당하는 새로운 `pixel_mask`를 생성해야 합니다.
+
+```py
+>>> def collate_fn(batch):
+... pixel_values = [item["pixel_values"] for item in batch]
+... encoding = image_processor.pad(pixel_values, return_tensors="pt")
+... labels = [item["labels"] for item in batch]
+... batch = {}
+... batch["pixel_values"] = encoding["pixel_values"]
+... batch["pixel_mask"] = encoding["pixel_mask"]
+... batch["labels"] = labels
+... return batch
+```
+
+## DETR 모델 학습시키기 [[training-the-DETR-model]]
+
+이전 섹션에서 대부분의 작업을 수행하여 이제 모델을 학습할 준비가 되었습니다!
+이 데이터 세트의 이미지는 리사이즈 후에도 여전히 용량이 크기 때문에, 이 모델을 미세 조정 하려면 적어도 하나의 GPU가 필요합니다.
+
+학습은 다음의 단계를 수행합니다:
+
+1. [`AutoModelForObjectDetection`]을 사용하여 전처리와 동일한 체크포인트를 사용하여 모델을 가져옵니다.
+2. [`TrainingArguments`]에서 학습 하이퍼파라미터를 정의합니다.
+3. 모델, 데이터 세트, 이미지 프로세서 및 데이터 콜레이터와 함께 [`Trainer`]에 훈련 인수를 전달합니다.
+4. [`~Trainer.train`]를 호출하여 모델을 미세 조정 합니다.
+
+전처리에 사용한 체크포인트와 동일한 체크포인트에서 모델을 가져올 때, 데이터 세트의 메타데이터에서 만든 `label2id`와 `id2label` 매핑을 전달해야 합니다.
+또한, `ignore_mismatched_sizes=True`를 지정하여 기존 분류 헤드(모델에서 분류에 사용되는 마지막 레이어)를 새 분류 헤드로 대체합니다.
+
+```py
+>>> from transformers import AutoModelForObjectDetection
+
+>>> model = AutoModelForObjectDetection.from_pretrained(
+... checkpoint,
+... id2label=id2label,
+... label2id=label2id,
+... ignore_mismatched_sizes=True,
+... )
+```
+
+[`TrainingArguments`]에서 `output_dir`을 사용하여 모델을 저장할 위치를 지정한 다음, 필요에 따라 하이퍼파라미터를 구성하세요.
+사용하지 않는 열을 제거하지 않도록 주의해야 합니다. 만약 `remove_unused_columns`가 `True`일 경우 이미지 열이 삭제됩니다.
+이미지 열이 없는 경우 `pixel_values`를 생성할 수 없기 때문에 `remove_unused_columns`를 `False`로 설정해야 합니다.
+모델을 Hub에 업로드하여 공유하려면 `push_to_hub`를 `True`로 설정하십시오(허깅페이스에 로그인하여 모델을 업로드해야 합니다).
+
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(
+... output_dir="detr-resnet-50_finetuned_cppe5",
+... per_device_train_batch_size=8,
+... num_train_epochs=10,
+... fp16=True,
+... save_steps=200,
+... logging_steps=50,
+... learning_rate=1e-5,
+... weight_decay=1e-4,
+... save_total_limit=2,
+... remove_unused_columns=False,
+... push_to_hub=True,
+... )
+```
+
+마지막으로 `model`, `training_args`, `collate_fn`, `image_processor`와 데이터 세트(`cppe5`)를 모두 가져온 후, [`~transformers.Trainer.train`]를 호출합니다.
+
+```py
+>>> from transformers import Trainer
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... data_collator=collate_fn,
+... train_dataset=cppe5["train"],
+... processing_class=image_processor,
+... )
+
+>>> trainer.train()
+```
+
+`training_args`에서 `push_to_hub`를 `True`로 설정한 경우, 학습 체크포인트는 허깅페이스 허브에 업로드됩니다.
+학습 완료 후, [`~transformers.Trainer.push_to_hub`] 메소드를 호출하여 최종 모델을 허깅페이스 허브에 업로드합니다.
+
+```py
+>>> trainer.push_to_hub()
+```
+
+## 평가하기 [[evaluate]]
+
+객체 탐지 모델은 일반적으로 일련의 COCO-스타일 지표로 평가됩니다.
+기존에 구현된 평가 지표 중 하나를 사용할 수도 있지만, 여기에서는 허깅페이스 허브에 푸시한 최종 모델을 평가하는 데 `torchvision`에서 제공하는 평가 지표를 사용합니다.
+
+`torchvision` 평가자(evaluator)를 사용하려면 실측값인 COCO 데이터 세트를 준비해야 합니다.
+COCO 데이터 세트를 빌드하는 API는 데이터를 특정 형식으로 저장해야 하므로, 먼저 이미지와 어노테이션을 디스크에 저장해야 합니다.
+학습을 위해 데이터를 준비할 때와 마찬가지로, cppe5["test"]에서의 어노테이션은 포맷을 맞춰야 합니다. 그러나 이미지는 그대로 유지해야 합니다.
+
+평가 단계는 약간의 작업이 필요하지만, 크게 세 가지 주요 단계로 나눌 수 있습니다.
+먼저, `cppe5["test"]` 세트를 준비합니다: 어노테이션을 포맷에 맞게 만들고 데이터를 디스크에 저장합니다.
+
+```py
+>>> import json
+
+
+>>> # format annotations the same as for training, no need for data augmentation
+>>> def val_formatted_anns(image_id, objects):
+... annotations = []
+... for i in range(0, len(objects["id"])):
+... new_ann = {
+... "id": objects["id"][i],
+... "category_id": objects["category"][i],
+... "iscrowd": 0,
+... "image_id": image_id,
+... "area": objects["area"][i],
+... "bbox": objects["bbox"][i],
+... }
+... annotations.append(new_ann)
+
+... return annotations
+
+
+>>> # Save images and annotations into the files torchvision.datasets.CocoDetection expects
+>>> def save_cppe5_annotation_file_images(cppe5):
+... output_json = {}
+... path_output_cppe5 = f"{os.getcwd()}/cppe5/"
+
+... if not os.path.exists(path_output_cppe5):
+... os.makedirs(path_output_cppe5)
+
+... path_anno = os.path.join(path_output_cppe5, "cppe5_ann.json")
+... categories_json = [{"supercategory": "none", "id": id, "name": id2label[id]} for id in id2label]
+... output_json["images"] = []
+... output_json["annotations"] = []
+... for example in cppe5:
+... ann = val_formatted_anns(example["image_id"], example["objects"])
+... output_json["images"].append(
+... {
+... "id": example["image_id"],
+... "width": example["image"].width,
+... "height": example["image"].height,
+... "file_name": f"{example['image_id']}.png",
+... }
+... )
+... output_json["annotations"].extend(ann)
+... output_json["categories"] = categories_json
+
+... with open(path_anno, "w") as file:
+... json.dump(output_json, file, ensure_ascii=False, indent=4)
+
+... for im, img_id in zip(cppe5["image"], cppe5["image_id"]):
+... path_img = os.path.join(path_output_cppe5, f"{img_id}.png")
+... im.save(path_img)
+
+... return path_output_cppe5, path_anno
+```
+
+다음으로, `cocoevaluator`와 함께 사용할 수 있는 `CocoDetection` 클래스의 인스턴스를 준비합니다.
+
+```py
+>>> import torchvision
+
+
+>>> class CocoDetection(torchvision.datasets.CocoDetection):
+... def __init__(self, img_folder, image_processor, ann_file):
+... super().__init__(img_folder, ann_file)
+... self.image_processor = image_processor
+
+... def __getitem__(self, idx):
+... # read in PIL image and target in COCO format
+... img, target = super(CocoDetection, self).__getitem__(idx)
+
+... # preprocess image and target: converting target to DETR format,
+... # resizing + normalization of both image and target)
+... image_id = self.ids[idx]
+... target = {"image_id": image_id, "annotations": target}
+... encoding = self.image_processor(images=img, annotations=target, return_tensors="pt")
+... pixel_values = encoding["pixel_values"].squeeze() # remove batch dimension
+... target = encoding["labels"][0] # remove batch dimension
+
+... return {"pixel_values": pixel_values, "labels": target}
+
+
+>>> im_processor = AutoImageProcessor.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
+
+>>> path_output_cppe5, path_anno = save_cppe5_annotation_file_images(cppe5["test"])
+>>> test_ds_coco_format = CocoDetection(path_output_cppe5, im_processor, path_anno)
+```
+
+마지막으로, 평가 지표를 가져와서 평가를 실행합니다.
+
+```py
+>>> import evaluate
+>>> from tqdm import tqdm
+
+>>> model = AutoModelForObjectDetection.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
+>>> module = evaluate.load("ybelkada/cocoevaluate", coco=test_ds_coco_format.coco)
+>>> val_dataloader = torch.utils.data.DataLoader(
+... test_ds_coco_format, batch_size=8, shuffle=False, num_workers=4, collate_fn=collate_fn
+... )
+
+>>> with torch.no_grad():
+... for idx, batch in enumerate(tqdm(val_dataloader)):
+... pixel_values = batch["pixel_values"]
+... pixel_mask = batch["pixel_mask"]
+
+... labels = [
+... {k: v for k, v in t.items()} for t in batch["labels"]
+... ] # these are in DETR format, resized + normalized
+
+... # forward pass
+... outputs = model(pixel_values=pixel_values, pixel_mask=pixel_mask)
+
+... orig_target_sizes = torch.stack([target["orig_size"] for target in labels], dim=0)
+... results = im_processor.post_process(outputs, orig_target_sizes) # convert outputs of model to Pascal VOC format (xmin, ymin, xmax, ymax)
+
+... module.add(prediction=results, reference=labels)
+... del batch
+
+>>> results = module.compute()
+>>> print(results)
+Accumulating evaluation results...
+DONE (t=0.08s).
+IoU metric: bbox
+ Average Precision (AP) @[ IoU=0.50:0.95 | area= all | maxDets=100 ] = 0.352
+ Average Precision (AP) @[ IoU=0.50 | area= all | maxDets=100 ] = 0.681
+ Average Precision (AP) @[ IoU=0.75 | area= all | maxDets=100 ] = 0.292
+ Average Precision (AP) @[ IoU=0.50:0.95 | area= small | maxDets=100 ] = 0.168
+ Average Precision (AP) @[ IoU=0.50:0.95 | area=medium | maxDets=100 ] = 0.208
+ Average Precision (AP) @[ IoU=0.50:0.95 | area= large | maxDets=100 ] = 0.429
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= all | maxDets= 1 ] = 0.274
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= all | maxDets= 10 ] = 0.484
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= all | maxDets=100 ] = 0.501
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= small | maxDets=100 ] = 0.191
+ Average Recall (AR) @[ IoU=0.50:0.95 | area=medium | maxDets=100 ] = 0.323
+ Average Recall (AR) @[ IoU=0.50:0.95 | area= large | maxDets=100 ] = 0.590
+```
+
+이러한 결과는 [`~transformers.TrainingArguments`]의 하이퍼파라미터를 조정하여 더욱 개선될 수 있습니다. 한번 시도해 보세요!
+
+## 추론하기 [[inference]]
+
+DETR 모델을 미세 조정 및 평가하고, 허깅페이스 허브에 업로드 했으므로 추론에 사용할 수 있습니다.
+
+미세 조정된 모델을 추론에 사용하는 가장 간단한 방법은 [`pipeline`]에서 모델을 사용하는 것입니다.
+모델과 함께 객체 탐지를 위한 파이프라인을 인스턴스화하고, 이미지를 전달하세요:
+
+```py
+>>> from transformers import pipeline
+>>> import requests
+
+>>> url = "https://i.imgur.com/2lnWoly.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> obj_detector = pipeline("object-detection", model="devonho/detr-resnet-50_finetuned_cppe5")
+>>> obj_detector(image)
+```
+
+만약 원한다면 수동으로 `pipeline`의 결과를 재현할 수 있습니다:
+
+```py
+>>> image_processor = AutoImageProcessor.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
+>>> model = AutoModelForObjectDetection.from_pretrained("devonho/detr-resnet-50_finetuned_cppe5")
+
+>>> with torch.no_grad():
+... inputs = image_processor(images=image, return_tensors="pt")
+... outputs = model(**inputs)
+... target_sizes = torch.tensor([image.size[::-1]])
+... results = image_processor.post_process_object_detection(outputs, threshold=0.5, target_sizes=target_sizes)[0]
+
+>>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+... box = [round(i, 2) for i in box.tolist()]
+... print(
+... f"Detected {model.config.id2label[label.item()]} with confidence "
+... f"{round(score.item(), 3)} at location {box}"
+... )
+Detected Coverall with confidence 0.566 at location [1215.32, 147.38, 4401.81, 3227.08]
+Detected Mask with confidence 0.584 at location [2449.06, 823.19, 3256.43, 1413.9]
+```
+
+결과를 시각화하겠습니다:
+```py
+>>> draw = ImageDraw.Draw(image)
+
+>>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+... box = [round(i, 2) for i in box.tolist()]
+... x, y, x2, y2 = tuple(box)
+... draw.rectangle((x, y, x2, y2), outline="red", width=1)
+... draw.text((x, y), model.config.id2label[label.item()], fill="white")
+
+>>> image
+```
+
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/prompting.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/prompting.md
new file mode 100644
index 0000000000000000000000000000000000000000..8f154dbe74c913ce34ae9a614a6705eb7b4ba13a
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/prompting.md
@@ -0,0 +1,384 @@
+
+
+
+# 대규모 언어 모델(LLM) 프롬프팅 가이드 [[llm-prompting-guide]]
+
+[[open-in-colab]]
+
+Falcon, LLaMA 등의 대규모 언어 모델은 사전 훈련된 트랜스포머 모델로, 초기에는 주어진 입력 텍스트에 대해 다음 토큰을 예측하도록 훈련됩니다. 이들은 보통 수십억 개의 매개변수를 가지고 있으며, 장기간에 걸쳐 수조 개의 토큰으로 훈련됩니다. 그 결과, 이 모델들은 매우 강력하고 다재다능해져서, 자연어 프롬프트로 모델에 지시하여 다양한 자연어 처리 작업을 즉시 수행할 수 있습니다.
+
+최적의 출력을 보장하기 위해 이러한 프롬프트를 설계하는 것을 흔히 "프롬프트 엔지니어링"이라고 합니다. 프롬프트 엔지니어링은 상당한 실험이 필요한 반복적인 과정입니다. 자연어는 프로그래밍 언어보다 훨씬 유연하고 표현력이 풍부하지만, 동시에 모호성을 초래할 수 있습니다. 또한, 자연어 프롬프트는 변화에 매우 민감합니다. 프롬프트의 사소한 수정만으로도 완전히 다른 출력이 나올 수 있습니다.
+
+모든 경우에 적용할 수 있는 정확한 프롬프트 생성 공식은 없지만, 연구자들은 더 일관되게 최적의 결과를 얻는 데 도움이 되는 여러 가지 모범 사례를 개발했습니다.
+
+이 가이드에서는 더 나은 대규모 언어 모델 프롬프트를 작성하고 다양한 자연어 처리 작업을 해결하는 데 도움이 되는 프롬프트 엔지니어링 모범 사례를 다룹니다:
+
+- [프롬프팅의 기초](#basics-of-prompting)
+- [대규모 언어 모델 프롬프팅의 모범 사례](#best-practices-of-llm-prompting)
+- [고급 프롬프팅 기법: 퓨샷(Few-shot) 프롬프팅과 생각의 사슬(Chain-of-thought, CoT) 기법](#advanced-prompting-techniques)
+- [프롬프팅 대신 미세 조정을 해야 하는 경우](#prompting-vs-fine-tuning)
+
+
+
+프롬프트 엔지니어링은 대규모 언어 모델 출력 최적화 과정의 일부일 뿐입니다. 또 다른 중요한 구성 요소는 최적의 텍스트 생성 전략을 선택하는 것입니다. 학습 가능한 매개변수를 수정하지 않고도 대규모 언어 모델이 텍스트를 생성하리 때 각각의 후속 토큰을 선택하는 방식을 사용자가 직접 정의할 수 있습니다. 텍스트 생성 매개변수를 조정함으로써 생성된 텍스트의 반복을 줄이고 더 일관되고 사람이 말하는 것 같은 텍스트를 만들 수 있습니다. 텍스트 생성 전략과 매개변수는 이 가이드의 범위를 벗어나지만, 다음 가이드에서 이러한 주제에 대해 자세히 알아볼 수 있습니다:
+
+* [대규모 언어 모델을 이용한 생성](../llm_tutorial)
+* [텍스트 생성 전략](../generation_strategies)
+
+
+
+## 프롬프팅의 기초 [[basics-of-prompting]]
+
+### 모델의 유형 [[types-of-models]]
+
+현대의 대부분의 대규모 언어 모델은 디코더만을 이용한 트랜스포머입니다. 예를 들어 [LLaMA](../model_doc/llama),
+[Llama2](../model_doc/llama2), [Falcon](../model_doc/falcon), [GPT2](../model_doc/gpt2) 등이 있습니다. 그러나 [Flan-T5](../model_doc/flan-t5)와 [BART](../model_doc/bart)와 같은 인코더-디코더 기반의 트랜스포머 대규모 언어 모델을 접할 수도 있습니다.
+
+인코더-디코더 기반의 모델은 일반적으로 출력이 입력에 **크게** 의존하는 생성 작업에 사용됩니다. 예를 들어, 번역과 요약 작업에 사용됩니다. 디코더 전용 모델은 다른 모든 유형의 생성 작업에 사용됩니다.
+
+파이프라인을 사용하여 대규모 언어 모델으로 텍스트를 생성할 때, 어떤 유형의 대규모 언어 모델을 사용하고 있는지 아는 것이 중요합니다. 왜냐하면 이들은 서로 다른 파이프라인을 사용하기 때문입니다.
+
+디코더 전용 모델로 추론을 실행하려면 `text-generation` 파이프라인을 사용하세요:
+
+```python
+>>> from transformers import pipeline
+>>> import torch
+
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+
+>>> generator = pipeline('text-generation', model = 'openai-community/gpt2')
+>>> prompt = "Hello, I'm a language model"
+
+>>> generator(prompt, max_length = 30)
+[{'generated_text': "Hello, I'm a language model programmer so you can use some of my stuff. But you also need some sort of a C program to run."}]
+```
+
+인코더-디코더로 추론을 실행하려면 `text2text-generation` 파이프라인을 사용하세요:
+
+```python
+>>> text2text_generator = pipeline("text2text-generation", model = 'google/flan-t5-base')
+>>> prompt = "Translate from English to French: I'm very happy to see you"
+
+>>> text2text_generator(prompt)
+[{'generated_text': 'Je suis très heureuse de vous rencontrer.'}]
+```
+
+### 기본 모델 vs 지시/채팅 모델 [[base-vs-instructchat-models]]
+
+🤗 Hub에서 최근 사용 가능한 대부분의 대규모 언어 모델 체크포인트는 기본 버전과 지시(또는 채팅) 두 가지 버전이 제공됩니다. 예를 들어, [`tiiuae/falcon-7b`](https://huggingface.co/tiiuae/falcon-7b)와 [`tiiuae/falcon-7b-instruct`](https://huggingface.co/tiiuae/falcon-7b-instruct)가 있습니다.
+
+기본 모델은 초기 프롬프트가 주어졌을 때 텍스트를 완성하는 데 탁월하지만, 지시를 따라야 하거나 대화형 사용이 필요한 자연어 처리작업에는 이상적이지 않습니다. 이때 지시(채팅) 버전이 필요합니다. 이러한 체크포인트는 사전 훈련된 기본 버전을 지시사항과 대화 데이터로 추가 미세 조정한 결과입니다. 이 추가적인 미세 조정으로 인해 많은 자연어 처리 작업에 더 적합한 선택이 됩니다.
+
+[`tiiuae/falcon-7b-instruct`](https://huggingface.co/tiiuae/falcon-7b-instruct)를 사용하여 일반적인 자연어 처리 작업을 해결하는 데 사용할 수 있는 몇 가지 간단한 프롬프트를 살펴보겠습니다.
+
+### 자연어 처리 작업 [[nlp-tasks]]
+
+먼저, 환경을 설정해 보겠습니다:
+
+```bash
+pip install -q transformers accelerate
+```
+
+다음으로, 적절한 파이프라인("text-generation")을 사용하여 모델을 로드하겠습니다:
+
+```python
+>>> from transformers import pipeline, AutoTokenizer
+>>> import torch
+
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+>>> model = "tiiuae/falcon-7b-instruct"
+
+>>> tokenizer = AutoTokenizer.from_pretrained(model)
+>>> pipe = pipeline(
+... "text-generation",
+... model=model,
+... tokenizer=tokenizer,
+... torch_dtype=torch.bfloat16,
+... device_map="auto",
+... )
+```
+
+
+
+Falcon 모델은 bfloat16 데이터 타입을 사용하여 훈련되었으므로, 같은 타입을 사용하는 것을 권장합니다. 이를 위해서는 최신 버전의 CUDA가 필요하며, 최신 그래픽 카드에서 가장 잘 작동합니다.
+
+
+
+이제 파이프라인을 통해 모델을 로드했으니, 프롬프트를 사용하여 자연어 처리 작업을 해결하는 방법을 살펴보겠습니다.
+
+#### 텍스트 분류 [[text-classification]]
+
+텍스트 분류의 가장 일반적인 형태 중 하나는 감정 분석입니다. 이는 텍스트 시퀀스에 "긍정적", "부정적" 또는 "중립적"과 같은 레이블을 할당합니다. 주어진 텍스트(영화 리뷰)를 분류하도록 모델에 지시하는 프롬프트를 작성해 보겠습니다. 먼저 지시사항을 제공한 다음, 분류할 텍스트를 지정하겠습니다. 여기서 주목할 점은 단순히 거기서 끝내지 않고, 응답의 시작 부분인 `"Sentiment: "`을 추가한다는 것입니다:
+
+```python
+>>> torch.manual_seed(0)
+>>> prompt = """Classify the text into neutral, negative or positive.
+... Text: This movie is definitely one of my favorite movies of its kind. The interaction between respectable and morally strong characters is an ode to chivalry and the honor code amongst thieves and policemen.
+... Sentiment:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=10,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result: Classify the text into neutral, negative or positive.
+Text: This movie is definitely one of my favorite movies of its kind. The interaction between respectable and morally strong characters is an ode to chivalry and the honor code amongst thieves and policemen.
+Sentiment:
+Positive
+```
+
+결과적으로, 우리가 지시사항에서 제공한 목록에서 선택된 분류 레이블이 정확하게 포함되어 생성된 것을 확인할 수 있습니다!
+
+
+프롬프트 외에도 `max_new_tokens` 매개변수를 전달하는 것을 볼 수 있습니다. 이 매개변수는 모델이 생성할 토큰의 수를 제어하며, [텍스트 생성 전략](../generation_strategies) 가이드에서 배울 수 있는 여러 텍스트 생성 매개변수 중 하나입니다.
+
+
+
+#### 개체명 인식 [[named-entity-recognition]]
+
+개체명 인식(Named Entity Recognition, NER)은 텍스트에서 인물, 장소, 조직과 같은 명명된 개체를 찾는 작업입니다. 프롬프트의 지시사항을 수정하여 대규모 언어 모델이 이 작업을 수행하도록 해보겠습니다. 여기서는 `return_full_text = False`로 설정하여 출력에 프롬프트가 포함되지 않도록 하겠습니다:
+
+```python
+>>> torch.manual_seed(1) # doctest: +IGNORE_RESULT
+>>> prompt = """Return a list of named entities in the text.
+... Text: The Golden State Warriors are an American professional basketball team based in San Francisco.
+... Named entities:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=15,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"{seq['generated_text']}")
+- Golden State Warriors
+- San Francisco
+```
+
+보시다시피, 모델이 주어진 텍스트에서 두 개의 명명된 개체를 정확하게 식별했습니다.
+
+#### 번역 [[translation]]
+
+대규모 언어 모델이 수행할 수 있는 또 다른 작업은 번역입니다. 이 작업을 위해 인코더-디코더 모델을 사용할 수 있지만, 여기서는 예시의 단순성을 위해 꽤 좋은 성능을 보이는 Falcon-7b-instruct를 계속 사용하겠습니다. 다시 한 번, 모델에게 영어에서 이탈리아어로 텍스트를 번역하도록 지시하는 기본적인 프롬프트를 작성하는 방법은 다음과 같습니다:
+
+```python
+>>> torch.manual_seed(2) # doctest: +IGNORE_RESULT
+>>> prompt = """Translate the English text to Italian.
+... Text: Sometimes, I've believed as many as six impossible things before breakfast.
+... Translation:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=20,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"{seq['generated_text']}")
+A volte, ho creduto a sei impossibili cose prima di colazione.
+```
+
+여기서는 모델이 출력을 생성할 때 조금 더 유연해질 수 있도록 `do_sample=True`와 `top_k=10`을 추가했습니다.
+
+#### 텍스트 요약 [[text-summarization]]
+
+번역과 마찬가지로, 텍스트 요약은 출력이 입력에 크게 의존하는 또 다른 생성 작업이며, 인코더-디코더 기반 모델이 더 나은 선택일 수 있습니다. 그러나 디코더 기반의 모델도 이 작업에 사용될 수 있습니다. 이전에는 프롬프트의 맨 처음에 지시사항을 배치했습니다. 하지만 프롬프트의 맨 끝도 지시사항을 넣을 적절한 위치가 될 수 있습니다. 일반적으로 지시사항을 양 극단 중 하나에 배치하는 것이 더 좋습니다.
+
+```python
+>>> torch.manual_seed(3) # doctest: +IGNORE_RESULT
+>>> prompt = """Permaculture is a design process mimicking the diversity, functionality and resilience of natural ecosystems. The principles and practices are drawn from traditional ecological knowledge of indigenous cultures combined with modern scientific understanding and technological innovations. Permaculture design provides a framework helping individuals and communities develop innovative, creative and effective strategies for meeting basic needs while preparing for and mitigating the projected impacts of climate change.
+... Write a summary of the above text.
+... Summary:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=30,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"{seq['generated_text']}")
+Permaculture is an ecological design mimicking natural ecosystems to meet basic needs and prepare for climate change. It is based on traditional knowledge and scientific understanding.
+```
+
+#### 질의 응답 [[question-answering]]
+
+질의 응답 작업을 위해 프롬프트를 다음과 같은 논리적 구성요소로 구조화할 수 있습니다. 지시사항, 맥락, 질문, 그리고 모델이 답변 생성을 시작하도록 유도하는 선도 단어나 구문(`"Answer:"`) 을 사용할 수 있습니다:
+
+```python
+>>> torch.manual_seed(4) # doctest: +IGNORE_RESULT
+>>> prompt = """Answer the question using the context below.
+... Context: Gazpacho is a cold soup and drink made of raw, blended vegetables. Most gazpacho includes stale bread, tomato, cucumbers, onion, bell peppers, garlic, olive oil, wine vinegar, water, and salt. Northern recipes often include cumin and/or pimentón (smoked sweet paprika). Traditionally, gazpacho was made by pounding the vegetables in a mortar with a pestle; this more laborious method is still sometimes used as it helps keep the gazpacho cool and avoids the foam and silky consistency of smoothie versions made in blenders or food processors.
+... Question: What modern tool is used to make gazpacho?
+... Answer:
+... """
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=10,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result: Modern tools often used to make gazpacho include
+```
+
+#### 추론 [[reasoning]]
+
+추론은 대규모 언어 모델(LLM)에게 가장 어려운 작업 중 하나이며, 좋은 결과를 얻기 위해서는 종종 [생각의 사슬(Chain-of-thought, CoT)](#chain-of-thought)과 같은 고급 프롬프팅 기법을 적용해야 합니다. 간단한 산술 작업에 대해 기본적인 프롬프트로 모델이 추론할 수 있는지 시도해 보겠습니다:
+
+```python
+>>> torch.manual_seed(5) # doctest: +IGNORE_RESULT
+>>> prompt = """There are 5 groups of students in the class. Each group has 4 students. How many students are there in the class?"""
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=30,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result:
+There are a total of 5 groups, so there are 5 x 4=20 students in the class.
+```
+
+정확한 답변이 생성되었습니다! 복잡성을 조금 높여보고 기본적인 프롬프트로도 여전히 해결할 수 있는지 확인해 보겠습니다:
+
+```python
+>>> torch.manual_seed(6)
+>>> prompt = """I baked 15 muffins. I ate 2 muffins and gave 5 muffins to a neighbor. My partner then bought 6 more muffins and ate 2. How many muffins do we now have?"""
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=10,
+... do_sample=True,
+... top_k=10,
+... return_full_text = False,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result:
+The total number of muffins now is 21
+```
+
+정답은 12여야 하는데 21이라는 잘못된 답변이 나왔습니다. 이 경우, 프롬프트가 너무 기본적이거나 모델의 크기가 작아서 생긴 문제일 수 있습니다. 우리는 Falcon의 가장 작은 버전을 선택했습니다. 추론은 큰 모델에게도 어려운 작업이지만, 더 큰 모델들이 더 나은 성능을 보일 가능성이 높습니다.
+
+## 대규모 언어 모델 프롬프트 작성의 모범 사례 [[best-practices-of-llm-prompting]]
+
+이 섹션에서는 프롬프트 결과를 향상시킬 수 있는 모범 사례 목록을 작성했습니다:
+
+* 작업할 모델을 선택할 때 최신 및 가장 강력한 모델이 더 나은 성능을 발휘할 가능성이 높습니다.
+* 간단하고 짧은 프롬프트로 시작하여 점진적으로 개선해 나가세요.
+* 프롬프트의 시작 부분이나 맨 끝에 지시사항을 배치하세요. 대규모 컨텍스트를 다룰 때, 모델들은 어텐션 복잡도가 2차적으로 증가하는 것을 방지하기 위해 다양한 최적화를 적용합니다. 이렇게 함으로써 모델이 프롬프트의 중간보다 시작이나 끝 부분에 더 주의를 기울일 수 있습니다.
+* 지시사항을 적용할 텍스트와 명확하게 분리해보세요. (이에 대해서는 다음 섹션에서 더 자세히 다룹니다.)
+* 작업과 원하는 결과에 대해 구체적이고 풍부한 설명을 제공하세요. 형식, 길이, 스타일, 언어 등을 명확하게 작성해야 합니다.
+* 모호한 설명과 지시사항을 피하세요.
+* "하지 말라"는 지시보다는 "무엇을 해야 하는지"를 말하는 지시를 사용하는 것이 좋습니다.
+* 첫 번째 단어를 쓰거나 첫 번째 문장을 시작하여 출력을 올바른 방향으로 "유도"하세요.
+* [퓨샷(Few-shot) 프롬프팅](#few-shot-prompting) 및 [생각의 사슬(Chain-of-thought, CoT)](#chain-of-thought) 같은 고급 기술을 사용해보세요.
+* 프롬프트의 견고성을 평가하기 위해 다른 모델로도 테스트하세요.
+* 프롬프트의 버전을 관리하고 성능을 추적하세요.
+
+## 고급 프롬프트 기법 [[advanced-prompting-techniques]]
+
+### 퓨샷(Few-shot) 프롬프팅 [[few-shot-prompting]]
+
+위 섹션의 기본 프롬프트들은 "제로샷(Zero-shot)" 프롬프트의 예시입니다. 이는 모델에 지시사항과 맥락은 주어졌지만, 해결책이 포함된 예시는 제공되지 않았다는 의미입니다. 지시 데이터셋으로 미세 조정된 대규모 언어 모델은 일반적으로 이러한 "제로샷" 작업에서 좋은 성능을 보입니다. 하지만 여러분의 작업이 더 복잡하거나 미묘한 차이가 있을 수 있고, 아마도 지시사항만으로는 모델이 포착하지 못하는 출력에 대한 요구사항이 있을 수 있습니다. 이런 경우에는 퓨샷(Few-shot) 프롬프팅이라는 기법을 시도해 볼 수 있습니다.
+
+퓨샷 프롬프팅에서는 프롬프트에 예시를 제공하여 모델에 더 많은 맥락을 주고 성능을 향상시킵니다. 이 예시들은 모델이 예시의 패턴을 따라 출력을 생성하도록 조건화합니다.
+
+다음은 예시입니다:
+
+```python
+>>> torch.manual_seed(0) # doctest: +IGNORE_RESULT
+>>> prompt = """Text: The first human went into space and orbited the Earth on April 12, 1961.
+... Date: 04/12/1961
+... Text: The first-ever televised presidential debate in the United States took place on September 28, 1960, between presidential candidates John F. Kennedy and Richard Nixon.
+... Date:"""
+
+>>> sequences = pipe(
+... prompt,
+... max_new_tokens=8,
+... do_sample=True,
+... top_k=10,
+... )
+
+>>> for seq in sequences:
+... print(f"Result: {seq['generated_text']}")
+Result: Text: The first human went into space and orbited the Earth on April 12, 1961.
+Date: 04/12/1961
+Text: The first-ever televised presidential debate in the United States took place on September 28, 1960, between presidential candidates John F. Kennedy and Richard Nixon.
+Date: 09/28/1960
+```
+
+위의 코드 스니펫에서는 모델에 원하는 출력을 보여주기 위해 단일 예시를 사용했으므로, 이를 "원샷(One-shot)" 프롬프팅이라고 부를 수 있습니다. 그러나 작업의 복잡성에 따라 하나 이상의 예시를 사용해야 할 수도 있습니다.
+
+퓨샷 프롬프팅 기법의 한계:
+- 대규모 언어 모델이 예시의 패턴을 파악할 수 있지만, 이 기법은 복잡한 추론 작업에는 잘 작동하지 않습니다.
+- 퓨샷 프롬프팅을 적용하면 프롬프트의 길이가 길어집니다. 토큰 수가 많은 프롬프트는 계산량과 지연 시간을 증가시킬 수 있으며 프롬프트 길이에도 제한이 있습니다.
+- 때로는 여러 예시가 주어질 때, 모델은 의도하지 않은 패턴을 학습할 수 있습니다. 예를 들어, 세 번째 영화 리뷰가 항상 부정적이라고 학습할 수 있습니다.
+
+### 생각의 사슬(Chain-of-thought, CoT) [[chain-of-thought]]
+
+생각의 사슬(Chain-of-thought, CoT) 프롬프팅은 모델이 중간 추론 단계를 생성하도록 유도하는 기법으로, 복잡한 추론 작업의 결과를 개선합니다.
+
+모델이 추론 단계를 생성하도록 유도하는 두 가지 방법이 있습니다:
+- 질문에 대한 상세한 답변을 예시로 제시하는 퓨샷 프롬프팅을 통해 모델에게 문제를 어떻게 해결해 나가는지 보여줍니다.
+- "단계별로 생각해 봅시다" 또는 "깊게 숨을 쉬고 문제를 단계별로 해결해 봅시다"와 같은 문구를 추가하여 모델에게 추론하도록 지시합니다.
+
+[reasoning section](#reasoning)의 머핀 예시에 생각의 사슬(Chain-of-thought, CoT) 기법을 적용하고 [HuggingChat](https://huggingface.co/chat/)에서 사용할 수 있는 (`tiiuae/falcon-180B-chat`)과 같은 더 큰 모델을 사용하면, 추론 결과가 크게 개선됩니다:
+
+```text
+단계별로 살펴봅시다:
+1. 처음에 15개의 머핀이 있습니다.
+2. 2개의 머핀을 먹으면 13개의 머핀이 남습니다.
+3. 이웃에게 5개의 머핀을 주면 8개의 머핀이 남습니다.
+4. 파트너가 6개의 머핀을 더 사오면 총 머핀 수는 14개가 됩니다.
+5. 파트너가 2개의 머핀을 먹으면 12개의 머핀이 남습니다.
+따라서, 현재 12개의 머핀이 있습니다.
+```
+
+## 프롬프팅 vs 미세 조정 [[prompting-vs-fine-tuning]]
+
+프롬프트를 최적화하여 훌륭한 결과를 얻을 수 있지만, 여전히 모델을 미세 조정하는 것이 더 좋을지 고민할 수 있습니다. 다음은 더 작은 모델을 미세 조정하는 것이 선호되는 시나리오입니다:
+
+- 도메인이 대규모 언어 모델이 사전 훈련된 것과 크게 다르고 광범위한 프롬프트 최적화로도 충분한 결과를 얻지 못한 경우.
+- 저자원 언어에서 모델이 잘 작동해야 하는 경우.
+- 엄격한 규제 하에 있는 민감한 데이터로 모델을 훈련해야 하는 경우.
+- 비용, 개인정보 보호, 인프라 또는 기타 제한으로 인해 작은 모델을 사용해야 하는 경우.
+
+위의 모든 예시에서, 모델을 미세 조정하기 위해 충분히 큰 도메인별 데이터셋을 이미 가지고 있거나 합리적인 비용으로 쉽게 얻을 수 있는지 확인해야 합니다. 또한 모델을 미세 조정할 충분한 시간과 자원이 필요합니다.
+
+만약 위의 예시들이 여러분의 경우에 해당하지 않는다면, 프롬프트를 최적화하는 것이 더 유익할 수 있습니다.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/question_answering.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/question_answering.md
new file mode 100644
index 0000000000000000000000000000000000000000..8309dd7d753244f355747d0bff29e564df2cde33
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/question_answering.md
@@ -0,0 +1,422 @@
+
+
+# 질의 응답(Question Answering)[[question-answering]]
+
+[[open-in-colab]]
+
+
+
+질의 응답 태스크는 주어진 질문에 대한 답변을 제공합니다. Alexa, Siri 또는 Google과 같은 가상 비서에게 날씨가 어떤지 물어본 적이 있다면 질의 응답 모델을 사용해본 적이 있을 것입니다. 질의 응답 태스크에는 일반적으로 두 가지 유형이 있습니다.
+
+- 추출적(Extractive) 질의 응답: 주어진 문맥에서 답변을 추출합니다.
+- 생성적(Abstractive) 질의 응답: 문맥에서 질문에 올바르게 답하는 답변을 생성합니다.
+
+이 가이드는 다음과 같은 방법들을 보여줍니다.
+
+1. 추출적 질의 응답을 하기 위해 [SQuAD](https://huggingface.co/datasets/squad) 데이터 세트에서 [DistilBERT](https://huggingface.co/distilbert/distilbert-base-uncased) 미세 조정하기
+2. 추론에 미세 조정된 모델 사용하기
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/question-answering)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에, 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+여러분의 모델을 업로드하고 커뮤니티에 공유할 수 있도록 Hugging Face 계정에 로그인하는 것이 좋습니다. 메시지가 표시되면 토큰을 입력해서 로그인합니다:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## SQuAD 데이터 세트 가져오기[[load-squad-dataset]]
+
+먼저 🤗 Datasets 라이브러리에서 SQuAD 데이터 세트의 일부를 가져옵니다. 이렇게 하면 전체 데이터 세트로 훈련하며 더 많은 시간을 할애하기 전에 모든 것이 잘 작동하는지 실험하고 확인할 수 있습니다.
+
+```py
+>>> from datasets import load_dataset
+
+>>> squad = load_dataset("squad", split="train[:5000]")
+```
+
+데이터 세트의 분할된 `train`을 [`~datasets.Dataset.train_test_split`] 메소드를 사용해 훈련 데이터 세트와 테스트 데이터 세트로 나누어줍니다:
+
+```py
+>>> squad = squad.train_test_split(test_size=0.2)
+```
+
+그리고나서 예시로 데이터를 하나 살펴봅니다:
+
+```py
+>>> squad["train"][0]
+{'answers': {'answer_start': [515], 'text': ['Saint Bernadette Soubirous']},
+ 'context': 'Architecturally, the school has a Catholic character. Atop the Main Building\'s gold dome is a golden statue of the Virgin Mary. Immediately in front of the Main Building and facing it, is a copper statue of Christ with arms upraised with the legend "Venite Ad Me Omnes". Next to the Main Building is the Basilica of the Sacred Heart. Immediately behind the basilica is the Grotto, a Marian place of prayer and reflection. It is a replica of the grotto at Lourdes, France where the Virgin Mary reputedly appeared to Saint Bernadette Soubirous in 1858. At the end of the main drive (and in a direct line that connects through 3 statues and the Gold Dome), is a simple, modern stone statue of Mary.',
+ 'id': '5733be284776f41900661182',
+ 'question': 'To whom did the Virgin Mary allegedly appear in 1858 in Lourdes France?',
+ 'title': 'University_of_Notre_Dame'
+}
+```
+
+이 중에서 몇 가지 중요한 항목이 있습니다:
+
+- `answers`: 답안 토큰의 시작 위치와 답안 텍스트
+- `context`: 모델이 답을 추출하는데 필요한 배경 지식
+- `question`: 모델이 답해야 하는 질문
+
+## 전처리[[preprocess]]
+
+
+
+다음 단계에서는 `question` 및 `context` 항목을 처리하기 위해 DistilBERT 토크나이저를 가져옵니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+질의 응답 태스크와 관련해서 특히 유의해야할 몇 가지 전처리 단계가 있습니다:
+
+1. 데이터 세트의 일부 예제에는 모델의 최대 입력 길이를 초과하는 매우 긴 `context`가 있을 수 있습니다. 긴 시퀀스를 다루기 위해서는, `truncation="only_second"`로 설정해 `context`만 잘라내면 됩니다.
+2. 그 다음, `return_offset_mapping=True`로 설정해 답변의 시작과 종료 위치를 원래의 `context`에 매핑합니다.
+3. 매핑을 완료하면, 이제 답변에서 시작 토큰과 종료 토큰을 찾을 수 있습니다. 오프셋의 어느 부분이 `question`과 `context`에 해당하는지 찾을 수 있도록 [`~tokenizers.Encoding.sequence_ids`] 메소드를 사용하세요.
+
+다음은 `answer`의 시작 토큰과 종료 토큰을 잘라내서 `context`에 매핑하는 함수를 만드는 방법입니다:
+
+```py
+>>> def preprocess_function(examples):
+... questions = [q.strip() for q in examples["question"]]
+... inputs = tokenizer(
+... questions,
+... examples["context"],
+... max_length=384,
+... truncation="only_second",
+... return_offsets_mapping=True,
+... padding="max_length",
+... )
+
+... offset_mapping = inputs.pop("offset_mapping")
+... answers = examples["answers"]
+... start_positions = []
+... end_positions = []
+
+... for i, offset in enumerate(offset_mapping):
+... answer = answers[i]
+... start_char = answer["answer_start"][0]
+... end_char = answer["answer_start"][0] + len(answer["text"][0])
+... sequence_ids = inputs.sequence_ids(i)
+
+... # Find the start and end of the context
+... idx = 0
+... while sequence_ids[idx] != 1:
+... idx += 1
+... context_start = idx
+... while sequence_ids[idx] == 1:
+... idx += 1
+... context_end = idx - 1
+
+... # If the answer is not fully inside the context, label it (0, 0)
+... if offset[context_start][0] > end_char or offset[context_end][1] < start_char:
+... start_positions.append(0)
+... end_positions.append(0)
+... else:
+... # Otherwise it's the start and end token positions
+... idx = context_start
+... while idx <= context_end and offset[idx][0] <= start_char:
+... idx += 1
+... start_positions.append(idx - 1)
+
+... idx = context_end
+... while idx >= context_start and offset[idx][1] >= end_char:
+... idx -= 1
+... end_positions.append(idx + 1)
+
+... inputs["start_positions"] = start_positions
+... inputs["end_positions"] = end_positions
+... return inputs
+```
+
+모든 데이터 세트에 전처리를 적용하려면, 🤗 Datasets [`~datasets.Dataset.map`] 함수를 사용하세요. `batched=True`로 설정해 데이터 세트의 여러 요소들을 한 번에 처리하면 `map` 함수의 속도를 빠르게 할 수 있습니다. 필요하지 않은 열은 모두 제거합니다:
+
+```py
+>>> tokenized_squad = squad.map(preprocess_function, batched=True, remove_columns=squad["train"].column_names)
+```
+
+이제 [`DefaultDataCollator`]를 이용해 예시 배치를 생성합니다. 🤗 Transformers의 다른 데이터 콜레이터(data collator)와 달리, [`DefaultDataCollator`]는 패딩과 같은 추가 전처리를 적용하지 않습니다:
+
+
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+```
+
+
+
+## 훈련[[train]]
+
+
+
+
+
+[`Trainer`]를 이용해 모델을 미세 조정하는 것에 익숙하지 않다면, [여기](../training#train-with-pytorch-trainer)에서 기초 튜토리얼을 살펴보세요!
+
+
+
+이제 모델 훈련을 시작할 준비가 되었습니다! [`AutoModelForQuestionAnswering`]으로 DistilBERT를 가져옵니다:
+
+```py
+>>> from transformers import AutoModelForQuestionAnswering, TrainingArguments, Trainer
+
+>>> model = AutoModelForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+이제 세 단계만 남았습니다:
+
+1. [`TrainingArguments`]에서 훈련 하이퍼파라미터를 정합니다. 꼭 필요한 매개변수는 모델을 저장할 위치를 지정하는 `output_dir` 입니다. `push_to_hub=True`로 설정해서 이 모델을 Hub로 푸시합니다 (모델을 업로드하려면 Hugging Face에 로그인해야 합니다).
+2. 모델, 데이터 세트, 토크나이저, 데이터 콜레이터와 함께 [`Trainer`]에 훈련 인수들을 전달합니다.
+3. [`~Trainer.train`]을 호출해서 모델을 미세 조정합니다.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_qa_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_squad["train"],
+... eval_dataset=tokenized_squad["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면, [`~transformers.Trainer.push_to_hub`] 매소드를 사용해 모델을 Hub에 공유해서 모든 사람들이 사용할 수 있게 공유해주세요:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras로 모델을 미세 조정하는 것에 익숙하지 않다면, [여기](../training#train-a-tensorflow-model-with-keras)에서 기초 튜토리얼을 살펴보세요!
+
+
+TensorFlow를 이용한 모델을 미세 조정하려면 옵티마이저 함수, 학습률 스케쥴 및 몇 가지 훈련 하이퍼파라미터를 설정하는 것부터 시작해야합니다:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_epochs = 2
+>>> total_train_steps = (len(tokenized_squad["train"]) // batch_size) * num_epochs
+>>> optimizer, schedule = create_optimizer(
+... init_lr=2e-5,
+... num_warmup_steps=0,
+... num_train_steps=total_train_steps,
+... )
+```
+
+그 다음 [`TFAutoModelForQuestionAnswering`]으로 DistilBERT를 가져옵니다:
+
+```py
+>>> from transformers import TFAutoModelForQuestionAnswering
+
+>>> model = TFAutoModelForQuestionAnswering("distilbert/distilbert-base-uncased")
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]을 사용해서 데이터 세트를 `tf.data.Dataset` 형식으로 변환합니다:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_squad["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_squad["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)로 훈련할 모델을 설정합니다:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+마지막으로 모델을 Hub로 푸시할 방법을 설정합니다. [`~transformers.PushToHubCallback`]에서 모델과 토크나이저를 푸시할 경로를 설정합니다:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_qa_model",
+... tokenizer=tokenizer,
+... )
+```
+
+드디어 모델 훈련을 시작할 준비가 되었습니다! 훈련 데이터 세트와 평가 데이터 세트, 에폭 수, 콜백을 설정한 후 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)을 이용해 모델을 미세 조정합니다:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=[callback])
+```
+훈련이 완료되면 모델이 자동으로 Hub에 업로드되어 누구나 사용할 수 있습니다!
+
+
+
+
+
+질의 응답을 위해 모델을 미세 조정하는 방법에 대한 더 자세한 예시는 [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb) 또는 [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering-tf.ipynb)을 참조하세요.
+
+
+
+## 평가[[evaluate]]
+
+질의 응답을 평가하려면 상당한 양의 후처리가 필요합니다. 시간이 너무 많이 걸리지 않도록 이 가이드에서는 평가 단계를 생략합니다. [`Trainer`]는 훈련 과정에서 평가 손실(evaluation loss)을 계속 계산하기 때문에 모델의 성능을 대략적으로 알 수 있습니다.
+
+시간에 여유가 있고 질의 응답 모델을 평가하는 방법에 관심이 있다면 🤗 Hugging Face Course의 [Question answering](https://huggingface.co/course/chapter7/7?fw=pt#postprocessing) 챕터를 살펴보세요!
+
+## 추론[[inference]]
+
+이제 모델을 미세 조정했으니 추론에 사용할 수 있습니다!
+
+질문과 모델이 예측하기 원하는 문맥(context)를 생각해보세요:
+
+```py
+>>> question = "How many programming languages does BLOOM support?"
+>>> context = "BLOOM has 176 billion parameters and can generate text in 46 languages natural languages and 13 programming languages."
+```
+
+추론을 위해 미세 조정한 모델을 테스트하는 가장 쉬운 방법은 [`pipeline`]을 사용하는 것 입니다. 모델을 사용해 질의 응답을 하기 위해서 `pipeline`을 인스턴스화하고 텍스트를 입력합니다:
+
+```py
+>>> from transformers import pipeline
+
+>>> question_answerer = pipeline("question-answering", model="my_awesome_qa_model")
+>>> question_answerer(question=question, context=context)
+{'score': 0.2058267742395401,
+ 'start': 10,
+ 'end': 95,
+ 'answer': '176 billion parameters and can generate text in 46 languages natural languages and 13'}
+```
+
+원한다면 `pipeline`의 결과를 직접 복제할 수도 있습니다:
+
+
+
+텍스트를 토큰화해서 PyTorch 텐서를 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_qa_model")
+>>> inputs = tokenizer(question, context, return_tensors="pt")
+```
+
+모델에 입력을 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import AutoModelForQuestionAnswering
+
+>>> model = AutoModelForQuestionAnswering.from_pretrained("my_awesome_qa_model")
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+```
+
+모델의 출력에서 시작 및 종료 위치가 어딘지 가장 높은 확률을 얻습니다:
+
+```py
+>>> answer_start_index = outputs.start_logits.argmax()
+>>> answer_end_index = outputs.end_logits.argmax()
+```
+
+예측된 토큰을 해독해서 답을 얻습니다:
+
+```py
+>>> predict_answer_tokens = inputs.input_ids[0, answer_start_index : answer_end_index + 1]
+>>> tokenizer.decode(predict_answer_tokens)
+'176 billion parameters and can generate text in 46 languages natural languages and 13'
+```
+
+
+텍스트를 토큰화해서 TensorFlow 텐서를 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_qa_model")
+>>> inputs = tokenizer(question, text, return_tensors="tf")
+```
+
+모델에 입력을 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForQuestionAnswering
+
+>>> model = TFAutoModelForQuestionAnswering.from_pretrained("my_awesome_qa_model")
+>>> outputs = model(**inputs)
+```
+
+모델의 출력에서 시작 및 종료 위치가 어딘지 가장 높은 확률을 얻습니다:
+
+```py
+>>> answer_start_index = int(tf.math.argmax(outputs.start_logits, axis=-1)[0])
+>>> answer_end_index = int(tf.math.argmax(outputs.end_logits, axis=-1)[0])
+```
+
+예측된 토큰을 해독해서 답을 얻습니다:
+
+```py
+>>> predict_answer_tokens = inputs.input_ids[0, answer_start_index : answer_end_index + 1]
+>>> tokenizer.decode(predict_answer_tokens)
+'176 billion parameters and can generate text in 46 languages natural languages and 13'
+```
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/semantic_segmentation.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/semantic_segmentation.md
new file mode 100644
index 0000000000000000000000000000000000000000..04a727448dacd392fc9d1ac449e53f52fe6a69a1
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/semantic_segmentation.md
@@ -0,0 +1,587 @@
+
+
+# 의미적 분할(Semantic segmentation)[[semantic-segmentation]]
+
+[[open-in-colab]]
+
+
+
+의미적 분할(semantic segmentation)은 이미지의 각 픽셀에 레이블 또는 클래스를 할당합니다. 분할(segmentation)에는 여러 종류가 있으며, 의미적 분할의 경우 동일한 물체의 고유 인스턴스를 구분하지 않습니다. 두 물체 모두 동일한 레이블이 지정됩니다(예시로, "car-1" 과 "car-2" 대신 "car"로 지정합니다).
+실생활에서 흔히 볼 수 있는 의미적 분할의 적용 사례로는 보행자와 중요한 교통 정보를 식별하는 자율 주행 자동차 학습, 의료 이미지의 세포와 이상 징후 식별, 그리고 위성 이미지의 환경 변화 모니터링등이 있습니다.
+
+이번 가이드에서 배울 내용은 다음과 같습니다:
+
+1. [SceneParse150](https://huggingface.co/datasets/scene_parse_150) 데이터 세트를 이용해 [SegFormer](https://huggingface.co/docs/transformers/main/en/model_doc/segformer#segformer) 미세 조정하기.
+2. 미세 조정된 모델을 추론에 사용하기.
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/image-segmentation)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 모든 라이브러리가 설치되었는지 확인하세요:
+
+```bash
+pip install -q datasets transformers evaluate
+```
+커뮤니티에 모델을 업로드하고 공유할 수 있도록 Hugging Face 계정에 로그인하는 것을 권장합니다. 프롬프트가 나타나면 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## SceneParse150 데이터 세트 불러오기[[load-sceneparse150-dataset]]
+
+🤗 Datasets 라이브러리에서 SceneParse150 데이터 세트의 더 작은 부분 집합을 가져오는 것으로 시작합니다. 이렇게 하면 데이터 세트 전체에 대한 훈련에 많은 시간을 할애하기 전에 실험을 통해 모든 것이 제대로 작동하는지 확인할 수 있습니다.
+
+```py
+>>> from datasets import load_dataset
+
+>>> ds = load_dataset("scene_parse_150", split="train[:50]")
+```
+
+데이터 세트의 `train`을 [`~datasets.Dataset.train_test_split`] 메소드를 사용하여 훈련 및 테스트 세트로 분할하세요:
+
+```py
+>>> ds = ds.train_test_split(test_size=0.2)
+>>> train_ds = ds["train"]
+>>> test_ds = ds["test"]
+```
+
+그리고 예시를 살펴보세요:
+
+```py
+>>> train_ds[0]
+{'image': ,
+ 'annotation': ,
+ 'scene_category': 368}
+```
+
+- `image`: 장면의 PIL 이미지입니다.
+- `annotation`: 분할 지도(segmentation map)의 PIL 이미지입니다. 모델의 타겟이기도 합니다.
+- `scene_category`: "주방" 또는 "사무실"과 같이 이미지 장면을 설명하는 카테고리 ID입니다. 이 가이드에서는 둘 다 PIL 이미지인 `image`와 `annotation`만을 사용합니다.
+
+나중에 모델을 설정할 때 유용하게 사용할 수 있도록 레이블 ID를 레이블 클래스에 매핑하는 사전도 만들고 싶을 것입니다. Hub에서 매핑을 다운로드하고 `id2label` 및 `label2id` 사전을 만드세요:
+
+```py
+>>> import json
+>>> from pathlib import Path
+>>> from huggingface_hub import hf_hub_download
+
+>>> repo_id = "huggingface/label-files"
+>>> filename = "ade20k-id2label.json"
+>>> id2label = json.loads(Path(hf_hub_download(repo_id, filename, repo_type="dataset")).read_text())
+>>> id2label = {int(k): v for k, v in id2label.items()}
+>>> label2id = {v: k for k, v in id2label.items()}
+>>> num_labels = len(id2label)
+```
+
+## 전처리하기[[preprocess]
+
+다음 단계는 모델에 사용할 이미지와 주석을 준비하기 위해 SegFormer 이미지 프로세서를 불러오는 것입니다. 우리가 사용하는 데이터 세트와 같은 일부 데이터 세트는 배경 클래스로 제로 인덱스를 사용합니다. 하지만 배경 클래스는 150개의 클래스에 실제로는 포함되지 않기 때문에 `do_reduce_labels=True` 를 설정해 모든 레이블에서 배경 클래스를 제거해야 합니다. 제로 인덱스는 `255`로 대체되므로 SegFormer의 손실 함수에서 무시됩니다:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> checkpoint = "nvidia/mit-b0"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint, do_reduce_labels=True)
+```
+
+
+
+
+이미지 데이터 세트에 데이터 증강을 적용하여 과적합에 대해 모델을 보다 강건하게 만드는 것이 일반적입니다. 이 가이드에서는 [torchvision](https://pytorch.org/vision/stable/index.html)의 [`ColorJitter`](https://pytorch.org/vision/stable/generated/torchvision.transforms.ColorJitter.html)를 사용하여 이미지의 색상 속성을 임의로 변경합니다. 하지만, 자신이 원하는 이미지 라이브러리를 사용할 수도 있습니다.
+
+```py
+>>> from torchvision.transforms import ColorJitter
+
+>>> jitter = ColorJitter(brightness=0.25, contrast=0.25, saturation=0.25, hue=0.1)
+```
+
+이제 모델에 사용할 이미지와 주석을 준비하기 위해 두 개의 전처리 함수를 만듭니다. 이 함수들은 이미지를 `pixel_values`로, 주석을 `labels`로 변환합니다. 훈련 세트의 경우 이미지 프로세서에 이미지를 제공하기 전에 `jitter`를 적용합니다. 테스트 세트의 경우 이미지 프로세서는 `images`를 자르고 정규화하며, 테스트 중에는 데이터 증강이 적용되지 않으므로 `labels`만 자릅니다.
+
+```py
+>>> def train_transforms(example_batch):
+... images = [jitter(x) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+
+
+>>> def val_transforms(example_batch):
+... images = [x for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+```
+
+모든 데이터 세트에 `jitter`를 적용하려면, 🤗 Datasets [`~datasets.Dataset.set_transform`] 함수를 사용하세요. 즉시 변환이 적용되기 때문에 더 빠르고 디스크 공간을 덜 차지합니다:
+
+```py
+>>> train_ds.set_transform(train_transforms)
+>>> test_ds.set_transform(val_transforms)
+```
+
+
+
+
+
+
+
+이미지 데이터 세트에 데이터 증강을 적용하여 과적합에 대해 모델을 보다 강건하게 만드는 것이 일반적입니다. 이 가이드에서는 [`tf.image`](https://www.tensorflow.org/api_docs/python/tf/image)를 사용하여 이미지의 색상 속성을 임의로 변경합니다. 하지만, 자신이 원하는 이미지 라이브러리를 사용할 수도 있습니다.
+
+별개의 두 변환 함수를 정의합니다:
+- 이미지 증강을 포함하는 학습 데이터 변환
+- 🤗 Transformers의 컴퓨터 비전 모델은 채널 우선 레이아웃을 기대하기 때문에, 이미지만 바꾸는 검증 데이터 변환
+
+```py
+>>> import tensorflow as tf
+
+
+>>> def aug_transforms(image):
+... image = tf.keras.utils.img_to_array(image)
+... image = tf.image.random_brightness(image, 0.25)
+... image = tf.image.random_contrast(image, 0.5, 2.0)
+... image = tf.image.random_saturation(image, 0.75, 1.25)
+... image = tf.image.random_hue(image, 0.1)
+... image = tf.transpose(image, (2, 0, 1))
+... return image
+
+
+>>> def transforms(image):
+... image = tf.keras.utils.img_to_array(image)
+... image = tf.transpose(image, (2, 0, 1))
+... return image
+```
+
+그런 다음 모델을 위해 두 개의 전처리 함수를 만들어 이미지 및 주석 배치를 준비합니다. 이 함수들은 이미지 변환을 적용하고 이전에 로드한 `image_processor`를 사용하여 이미지를 `pixel_values`로, 주석을 `label`로 변환합니다. `ImageProcessor` 는 이미지의 크기 조정과 정규화도 처리합니다.
+
+```py
+>>> def train_transforms(example_batch):
+... images = [aug_transforms(x.convert("RGB")) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+
+
+>>> def val_transforms(example_batch):
+... images = [transforms(x.convert("RGB")) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+```
+
+전체 데이터 집합에 전처리 변환을 적용하려면 🤗 Datasets [`~datasets.Dataset.set_transform`] 함수를 사용하세요.
+즉시 변환이 적용되기 때문에 더 빠르고 디스크 공간을 덜 차지합니다:
+
+```py
+>>> train_ds.set_transform(train_transforms)
+>>> test_ds.set_transform(val_transforms)
+```
+
+
+
+## 평가하기[[evaluate]]
+
+훈련 중에 메트릭을 포함하면 모델의 성능을 평가하는 데 도움이 되는 경우가 많습니다. 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하여 평가 방법을 빠르게 로드할 수 있습니다. 이 태스크에서는 [mean Intersection over Union](https://huggingface.co/spaces/evaluate-metric/accuracy) (IoU) 메트릭을 로드하세요 (메트릭을 로드하고 계산하는 방법에 대해 자세히 알아보려면 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour)를 살펴보세요).
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("mean_iou")
+```
+
+그런 다음 메트릭을 [`~evaluate.EvaluationModule.compute`]하는 함수를 만듭니다. 예측을 먼저 로짓으로 변환한 다음, 레이블의 크기에 맞게 모양을 다시 지정해야 [`~evaluate.EvaluationModule.compute`]를 호출할 수 있습니다:
+
+
+
+
+```py
+>>> import numpy as np
+>>> import torch
+>>> from torch import nn
+
+>>> def compute_metrics(eval_pred):
+... with torch.no_grad():
+... logits, labels = eval_pred
+... logits_tensor = torch.from_numpy(logits)
+... logits_tensor = nn.functional.interpolate(
+... logits_tensor,
+... size=labels.shape[-2:],
+... mode="bilinear",
+... align_corners=False,
+... ).argmax(dim=1)
+
+... pred_labels = logits_tensor.detach().cpu().numpy()
+... metrics = metric.compute(
+... predictions=pred_labels,
+... references=labels,
+... num_labels=num_labels,
+... ignore_index=255,
+... reduce_labels=False,
+... )
+... for key, value in metrics.items():
+... if isinstance(value, np.ndarray):
+... metrics[key] = value.tolist()
+... return metrics
+```
+
+
+
+
+
+
+
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... logits = tf.transpose(logits, perm=[0, 2, 3, 1])
+... logits_resized = tf.image.resize(
+... logits,
+... size=tf.shape(labels)[1:],
+... method="bilinear",
+... )
+
+... pred_labels = tf.argmax(logits_resized, axis=-1)
+... metrics = metric.compute(
+... predictions=pred_labels,
+... references=labels,
+... num_labels=num_labels,
+... ignore_index=-1,
+... reduce_labels=image_processor.do_reduce_labels,
+... )
+
+... per_category_accuracy = metrics.pop("per_category_accuracy").tolist()
+... per_category_iou = metrics.pop("per_category_iou").tolist()
+
+... metrics.update({f"accuracy_{id2label[i]}": v for i, v in enumerate(per_category_accuracy)})
+... metrics.update({f"iou_{id2label[i]}": v for i, v in enumerate(per_category_iou)})
+... return {"val_" + k: v for k, v in metrics.items()}
+```
+
+
+
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었습니다. 트레이닝을 설정할 때 이 함수로 돌아가게 됩니다.
+
+## 학습하기[[train]]
+
+
+
+
+만약 [`Trainer`]를 사용해 모델을 미세 조정하는 것에 익숙하지 않다면, [여기](../training#finetune-with-trainer)에서 기본 튜토리얼을 살펴보세요!
+
+
+
+이제 모델 학습을 시작할 준비가 되었습니다! [`AutoModelForSemanticSegmentation`]로 SegFormer를 불러오고, 모델에 레이블 ID와 레이블 클래스 간의 매핑을 전달합니다:
+
+```py
+>>> from transformers import AutoModelForSemanticSegmentation, TrainingArguments, Trainer
+
+>>> model = AutoModelForSemanticSegmentation.from_pretrained(checkpoint, id2label=id2label, label2id=label2id)
+```
+
+이제 세 단계만 남았습니다:
+
+1. 학습 하이퍼파라미터를 [`TrainingArguments`]에 정의합니다. `image` 열이 삭제되기 때문에 사용하지 않는 열을 제거하지 않는 것이 중요합니다. `image` 열이 없으면 `pixel_values`을 생성할 수 없습니다. 이런 경우를 방지하려면 `remove_unused_columns=False`로 설정하세요! 유일하게 필요한 다른 매개변수는 모델을 저장할 위치를 지정하는 `output_dir`입니다. `push_to_hub=True`를 설정하여 이 모델을 Hub에 푸시합니다(모델을 업로드하려면 Hugging Face에 로그인해야 합니다). 각 에포크가 끝날 때마다 [`Trainer`]가 IoU 메트릭을 평가하고 학습 체크포인트를 저장합니다.
+2. 모델, 데이터 세트, 토크나이저, 데이터 콜레이터, `compute_metrics` 함수와 함께 학습 인자를 [`Trainer`]에 전달하세요.
+3. 모델을 미세 조정하기 위해 [`~Trainer.train`]를 호출하세요.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="segformer-b0-scene-parse-150",
+... learning_rate=6e-5,
+... num_train_epochs=50,
+... per_device_train_batch_size=2,
+... per_device_eval_batch_size=2,
+... save_total_limit=3,
+... eval_strategy="steps",
+... save_strategy="steps",
+... save_steps=20,
+... eval_steps=20,
+... logging_steps=1,
+... eval_accumulation_steps=5,
+... remove_unused_columns=False,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=train_ds,
+... eval_dataset=test_ds,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+학습이 완료되면, 누구나 모델을 사용할 수 있도록 [`~transformers.Trainer.push_to_hub`] 메서드를 사용해 Hub에 모델을 공유하세요:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+
+
+Keras로 모델을 미세 조정하는 데 익숙하지 않은 경우, 먼저 [기본 튜토리얼](../training#train-a-tensorflow-model-with-keras)을 확인해보세요!
+
+
+
+TensorFlow에서 모델을 미세 조정하려면 다음 단계를 따르세요:
+1. 학습 하이퍼파라미터를 정의하고 옵티마이저와 학습률 스케쥴러를 설정하세요.
+2. 사전 학습된 모델을 인스턴스화하세요.
+3. 🤗 Dataset을 `tf.data.Dataset`로 변환하세요.
+4. 모델을 컴파일하세요.
+5. 콜백을 추가하여 메트릭을 계산하고 🤗 Hub에 모델을 업로드하세요.
+6. `fit()` 메서드를 사용하여 훈련을 실행하세요.
+
+하이퍼파라미터, 옵티마이저, 학습률 스케쥴러를 정의하는 것으로 시작하세요:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 2
+>>> num_epochs = 50
+>>> num_train_steps = len(train_ds) * num_epochs
+>>> learning_rate = 6e-5
+>>> weight_decay_rate = 0.01
+
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=learning_rate,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=weight_decay_rate,
+... num_warmup_steps=0,
+... )
+```
+
+그런 다음 레이블 매핑과 함께 [`TFAutoModelForSemanticSegmentation`]을 사용하여 SegFormer를 불러오고 옵티마이저로 컴파일합니다. 트랜스포머 모델은 모두 디폴트로 태스크 관련 손실 함수가 있으므로 원치 않으면 지정할 필요가 없습니다:
+
+```py
+>>> from transformers import TFAutoModelForSemanticSegmentation
+
+>>> model = TFAutoModelForSemanticSegmentation.from_pretrained(
+... checkpoint,
+... id2label=id2label,
+... label2id=label2id,
+... )
+>>> model.compile(optimizer=optimizer) # 손실 함수 인자가 없습니다!
+```
+
+[`~datasets.Dataset.to_tf_dataset`] 와 [`DefaultDataCollator`]를 사용해 데이터 세트를 `tf.data.Dataset` 포맷으로 변환하세요:
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+
+>>> tf_train_dataset = train_ds.to_tf_dataset(
+... columns=["pixel_values", "label"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+
+>>> tf_eval_dataset = test_ds.to_tf_dataset(
+... columns=["pixel_values", "label"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+```
+
+예측으로 정확도를 계산하고 모델을 🤗 Hub로 푸시하려면 [Keras callbacks](../main_classes/keras_callbacks)를 사용하세요. `compute_metrics` 함수를 [`KerasMetricCallback`]에 전달하고, 모델 업로드를 위해 [`PushToHubCallback`]를 사용하세요:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback, PushToHubCallback
+
+>>> metric_callback = KerasMetricCallback(
+... metric_fn=compute_metrics, eval_dataset=tf_eval_dataset, batch_size=batch_size, label_cols=["labels"]
+... )
+
+>>> push_to_hub_callback = PushToHubCallback(output_dir="scene_segmentation", tokenizer=image_processor)
+
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+이제 모델을 훈련할 준비가 되었습니다! 훈련 및 검증 데이터 세트, 에포크 수와 함께 `fit()`을 호출하고, 콜백을 사용하여 모델을 미세 조정합니다:
+
+```py
+>>> model.fit(
+... tf_train_dataset,
+... validation_data=tf_eval_dataset,
+... callbacks=callbacks,
+... epochs=num_epochs,
+... )
+```
+
+축하합니다! 모델을 미세 조정하고 🤗 Hub에 공유했습니다. 이제 추론에 사용할 수 있습니다!
+
+
+
+
+
+## 추론하기[[inference]]
+
+이제 모델을 미세 조정했으니 추론에 사용할 수 있습니다!
+
+추론할 이미지를 로드하세요:
+
+```py
+>>> image = ds[0]["image"]
+>>> image
+```
+
+
+
+
+
+
+
+
+추론을 위해 미세 조정한 모델을 시험해 보는 가장 간단한 방법은 [`pipeline`]에서 사용하는 것입니다. 모델을 사용하여 이미지 분할을 위한 `pipeline`을 인스턴스화하고 이미지를 전달합니다:
+
+```py
+>>> from transformers import pipeline
+
+>>> segmenter = pipeline("image-segmentation", model="my_awesome_seg_model")
+>>> segmenter(image)
+[{'score': None,
+ 'label': 'wall',
+ 'mask': },
+ {'score': None,
+ 'label': 'sky',
+ 'mask': },
+ {'score': None,
+ 'label': 'floor',
+ 'mask': },
+ {'score': None,
+ 'label': 'ceiling',
+ 'mask': },
+ {'score': None,
+ 'label': 'bed ',
+ 'mask': },
+ {'score': None,
+ 'label': 'windowpane',
+ 'mask': },
+ {'score': None,
+ 'label': 'cabinet',
+ 'mask': },
+ {'score': None,
+ 'label': 'chair',
+ 'mask': },
+ {'score': None,
+ 'label': 'armchair',
+ 'mask': }]
+```
+원하는 경우 `pipeline`의 결과를 수동으로 복제할 수도 있습니다. 이미지 프로세서로 이미지를 처리하고 `pixel_values`을 GPU에 배치합니다:
+
+```py
+>>> device = torch.device("cuda" if torch.cuda.is_available() else "cpu") # 가능하다면 GPU를 사용하고, 그렇지 않다면 CPU를 사용하세요
+>>> encoding = image_processor(image, return_tensors="pt")
+>>> pixel_values = encoding.pixel_values.to(device)
+```
+
+모델에 입력을 전달하고 `logits`를 반환합니다:
+
+```py
+>>> outputs = model(pixel_values=pixel_values)
+>>> logits = outputs.logits.cpu()
+```
+그런 다음 로짓의 크기를 원본 이미지 크기로 다시 조정합니다:
+
+```py
+>>> upsampled_logits = nn.functional.interpolate(
+... logits,
+... size=image.size[::-1],
+... mode="bilinear",
+... align_corners=False,
+... )
+
+>>> pred_seg = upsampled_logits.argmax(dim=1)[0]
+```
+
+
+
+
+
+
+이미지 프로세서를 로드하여 이미지를 전처리하고 입력을 TensorFlow 텐서로 반환합니다:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("MariaK/scene_segmentation")
+>>> inputs = image_processor(image, return_tensors="tf")
+```
+
+모델에 입력을 전달하고 `logits`를 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForSemanticSegmentation
+
+>>> model = TFAutoModelForSemanticSegmentation.from_pretrained("MariaK/scene_segmentation")
+>>> logits = model(**inputs).logits
+```
+
+그런 다음 로그를 원본 이미지 크기로 재조정하고 클래스 차원에 argmax를 적용합니다:
+
+```py
+>>> logits = tf.transpose(logits, [0, 2, 3, 1])
+
+>>> upsampled_logits = tf.image.resize(
+... logits,
+... # `image.size`가 너비와 높이를 반환하기 때문에 `image`의 모양을 반전시킵니다
+... image.size[::-1],
+... )
+
+>>> pred_seg = tf.math.argmax(upsampled_logits, axis=-1)[0]
+```
+
+
+
+
+결과를 시각화하려면 [dataset color palette](https://github.com/tensorflow/models/blob/3f1ca33afe3c1631b733ea7e40c294273b9e406d/research/deeplab/utils/get_dataset_colormap.py#L51)를 각 클래스를 RGB 값에 매핑하는 `ade_palette()`로 로드합니다. 그런 다음 이미지와 예측된 분할 지도(segmentation map)을 결합하여 구성할 수 있습니다:
+
+```py
+>>> import matplotlib.pyplot as plt
+>>> import numpy as np
+
+>>> color_seg = np.zeros((pred_seg.shape[0], pred_seg.shape[1], 3), dtype=np.uint8)
+>>> palette = np.array(ade_palette())
+>>> for label, color in enumerate(palette):
+... color_seg[pred_seg == label, :] = color
+>>> color_seg = color_seg[..., ::-1] # BGR로 변환
+
+>>> img = np.array(image) * 0.5 + color_seg * 0.5 # 분할 지도으로 이미지 구성
+>>> img = img.astype(np.uint8)
+
+>>> plt.figure(figsize=(15, 10))
+>>> plt.imshow(img)
+>>> plt.show()
+```
+
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/sequence_classification.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/sequence_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..11dae1a965a4f2634cf304bb8c805715e2791f9b
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/sequence_classification.md
@@ -0,0 +1,389 @@
+
+
+# 텍스트 분류[[text-classification]]
+
+[[open-in-colab]]
+
+
+
+텍스트 분류는 자연어 처리의 일종으로, 텍스트에 레이블 또는 클래스를 지정하는 작업입니다. 많은 대기업이 다양한 실용적인 응용 분야에서 텍스트 분류를 운영하고 있습니다. 가장 인기 있는 텍스트 분류 형태 중 하나는 감성 분석으로, 텍스트 시퀀스에 🙂 긍정, 🙁 부정 또는 😐 중립과 같은 레이블을 지정합니다.
+
+이 가이드에서 학습할 내용은:
+
+1. [IMDb](https://huggingface.co/datasets/imdb) 데이터셋에서 [DistilBERT](https://huggingface.co/distilbert/distilbert-base-uncased)를 파인 튜닝하여 영화 리뷰가 긍정적인지 부정적인지 판단합니다.
+2. 추론을 위해 파인 튜닝 모델을 사용합니다.
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/text-classification)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에, 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+Hugging Face 계정에 로그인하여 모델을 업로드하고 커뮤니티에 공유하는 것을 권장합니다. 메시지가 표시되면, 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## IMDb 데이터셋 가져오기[[load-imdb-dataset]]
+
+먼저 🤗 Datasets 라이브러리에서 IMDb 데이터셋을 가져옵니다:
+
+```py
+>>> from datasets import load_dataset
+
+>>> imdb = load_dataset("imdb")
+```
+
+그런 다음 예시를 살펴봅시다:
+
+```py
+>>> imdb["test"][0]
+{
+ "label": 0,
+ "text": "I love sci-fi and am willing to put up with a lot. Sci-fi movies/TV are usually underfunded, under-appreciated and misunderstood. I tried to like this, I really did, but it is to good TV sci-fi as Babylon 5 is to Star Trek (the original). Silly prosthetics, cheap cardboard sets, stilted dialogues, CG that doesn't match the background, and painfully one-dimensional characters cannot be overcome with a 'sci-fi' setting. (I'm sure there are those of you out there who think Babylon 5 is good sci-fi TV. It's not. It's clichéd and uninspiring.) While US viewers might like emotion and character development, sci-fi is a genre that does not take itself seriously (cf. Star Trek). It may treat important issues, yet not as a serious philosophy. It's really difficult to care about the characters here as they are not simply foolish, just missing a spark of life. Their actions and reactions are wooden and predictable, often painful to watch. The makers of Earth KNOW it's rubbish as they have to always say \"Gene Roddenberry's Earth...\" otherwise people would not continue watching. Roddenberry's ashes must be turning in their orbit as this dull, cheap, poorly edited (watching it without advert breaks really brings this home) trudging Trabant of a show lumbers into space. Spoiler. So, kill off a main character. And then bring him back as another actor. Jeeez! Dallas all over again.",
+}
+```
+
+이 데이터셋에는 두 가지 필드가 있습니다:
+
+- `text`: 영화 리뷰 텍스트
+- `label`: `0`은 부정적인 리뷰, `1`은 긍정적인 리뷰를 나타냅니다.
+
+## 전처리[[preprocess]]
+
+다음 단계는 DistilBERT 토크나이저를 가져와서 `text` 필드를 전처리하는 것입니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+`text`를 토큰화하고 시퀀스가 DistilBERT의 최대 입력 길이보다 길지 않도록 자르기 위한 전처리 함수를 생성하세요:
+
+```py
+>>> def preprocess_function(examples):
+... return tokenizer(examples["text"], truncation=True)
+```
+
+전체 데이터셋에 전처리 함수를 적용하려면, 🤗 Datasets [`~datasets.Dataset.map`] 함수를 사용하세요. 데이터셋의 여러 요소를 한 번에 처리하기 위해 `batched=True`로 설정함으로써 데이터셋 `map`를 더 빠르게 처리할 수 있습니다:
+
+```py
+tokenized_imdb = imdb.map(preprocess_function, batched=True)
+```
+
+이제 [`DataCollatorWithPadding`]를 사용하여 예제 배치를 만들어봅시다. 데이터셋 전체를 최대 길이로 패딩하는 대신, *동적 패딩*을 사용하여 배치에서 가장 긴 길이에 맞게 문장을 패딩하는 것이 효율적입니다.
+
+
+
+```py
+>>> from transformers import DataCollatorWithPadding
+
+>>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+```
+
+
+```py
+>>> from transformers import DataCollatorWithPadding
+
+>>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer, return_tensors="tf")
+```
+
+
+
+## 평가하기[[evaluate]]
+
+훈련 중 모델의 성능을 평가하기 위해 메트릭을 포함하는 것이 유용합니다. 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하여 빠르게 평가 방법을 로드할 수 있습니다. 이 작업에서는 [accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) 메트릭을 가져옵니다. (메트릭을 가져오고 계산하는 방법에 대해서는 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하세요):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+그런 다음 `compute_metrics` 함수를 만들어서 예측과 레이블을 계산하여 정확도를 계산하도록 [`~evaluate.EvaluationModule.compute`]를 호출합니다:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... predictions = np.argmax(predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=labels)
+```
+
+이제 `compute_metrics` 함수는 준비되었고, 훈련 과정을 설정할 때 다시 살펴볼 예정입니다.
+
+## 훈련[[train]]
+
+모델을 훈련하기 전에, `id2label`와 `label2id`를 사용하여 예상되는 id와 레이블의 맵을 생성하세요:
+
+```py
+>>> id2label = {0: "NEGATIVE", 1: "POSITIVE"}
+>>> label2id = {"NEGATIVE": 0, "POSITIVE": 1}
+```
+
+
+
+
+
+[`Trainer`]를 사용하여 모델을 파인 튜닝하는 방법에 익숙하지 않은 경우, [여기](../training#train-with-pytorch-trainer)의 기본 튜토리얼을 확인하세요!
+
+
+
+이제 모델을 훈련시킬 준비가 되었습니다! [`AutoModelForSequenceClassification`]로 DistilBERT를 가쳐오고 예상되는 레이블 수와 레이블 매핑을 지정하세요:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=2, id2label=id2label, label2id=label2id
+... )
+```
+
+이제 세 단계만 거치면 끝입니다:
+
+1. [`TrainingArguments`]에서 하이퍼파라미터를 정의하세요. `output_dir`는 모델을 저장할 위치를 지정하는 유일한 파라미터입니다. 이 모델을 Hub에 업로드하기 위해 `push_to_hub=True`를 설정합니다. (모델을 업로드하기 위해 Hugging Face에 로그인해야합니다.) 각 에폭이 끝날 때마다, [`Trainer`]는 정확도를 평가하고 훈련 체크포인트를 저장합니다.
+2. [`Trainer`]에 훈련 인수와 모델, 데이터셋, 토크나이저, 데이터 수집기 및 `compute_metrics` 함수를 전달하세요.
+3. [`~Trainer.train`]를 호출하여 모델은 파인 튜닝하세요.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_model",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=2,
+... weight_decay=0.01,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... load_best_model_at_end=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_imdb["train"],
+... eval_dataset=tokenized_imdb["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+
+
+[`Trainer`]는 `tokenizer`를 전달하면 기본적으로 동적 매핑을 적용합니다. 이 경우, 명시적으로 데이터 수집기를 지정할 필요가 없습니다.
+
+
+
+훈련이 완료되면, [`~transformers.Trainer.push_to_hub`] 메소드를 사용하여 모델을 Hub에 공유할 수 있습니다.
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras를 사용하여 모델을 파인 튜닝하는 방법에 익숙하지 않은 경우, [여기](../training#train-a-tensorflow-model-with-keras)의 기본 튜토리얼을 확인하세요!
+
+
+TensorFlow에서 모델을 파인 튜닝하려면, 먼저 옵티마이저 함수와 학습률 스케쥴, 그리고 일부 훈련 하이퍼파라미터를 설정해야 합니다:
+
+```py
+>>> from transformers import create_optimizer
+>>> import tensorflow as tf
+
+>>> batch_size = 16
+>>> num_epochs = 5
+>>> batches_per_epoch = len(tokenized_imdb["train"]) // batch_size
+>>> total_train_steps = int(batches_per_epoch * num_epochs)
+>>> optimizer, schedule = create_optimizer(init_lr=2e-5, num_warmup_steps=0, num_train_steps=total_train_steps)
+```
+
+그런 다음 [`TFAutoModelForSequenceClassification`]을 사용하여 DistilBERT를 로드하고, 예상되는 레이블 수와 레이블 매핑을 로드할 수 있습니다:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=2, id2label=id2label, label2id=label2id
+... )
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]을 사용하여 데이터셋을 `tf.data.Dataset` 형식으로 변환합니다:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_imdb["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_imdb["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)를 사용하여 훈련할 모델을 구성합니다:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+훈련을 시작하기 전에 설정해야할 마지막 두 가지는 예측에서 정확도를 계산하고, 모델을 Hub에 업로드할 방법을 제공하는 것입니다. 모두 [Keras callbacks](../main_classes/keras_callbacks)를 사용하여 수행됩니다.
+
+[`~transformers.KerasMetricCallback`]에 `compute_metrics`를 전달하여 정확도를 높입니다.
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+[`~transformers.PushToHubCallback`]에서 모델과 토크나이저를 업로드할 위치를 지정합니다:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_model",
+... tokenizer=tokenizer,
+... )
+```
+
+그런 다음 콜백을 함께 묶습니다:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+드디어, 모델 훈련을 시작할 준비가 되었습니다! [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)에 훈련 데이터셋, 검증 데이터셋, 에폭의 수 및 콜백을 전달하여 파인 튜닝합니다:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=callbacks)
+```
+
+훈련이 완료되면, 모델이 자동으로 Hub에 업로드되어 모든 사람이 사용할 수 있습니다!
+
+
+
+
+
+텍스트 분류를 위한 모델을 파인 튜닝하는 자세한 예제는 다음 [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb) 또는 [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification-tf.ipynb)를 참조하세요.
+
+
+
+## 추론[[inference]]
+
+좋아요, 이제 모델을 파인 튜닝했으니 추론에 사용할 수 있습니다!
+
+추론을 수행하고자 하는 텍스트를 가져와봅시다:
+
+```py
+>>> text = "This was a masterpiece. Not completely faithful to the books, but enthralling from beginning to end. Might be my favorite of the three."
+```
+
+파인 튜닝된 모델로 추론을 시도하는 가장 간단한 방법은 [`pipeline`]를 사용하는 것입니다. 모델로 감정 분석을 위한 `pipeline`을 인스턴스화하고, 텍스트를 전달해보세요:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("sentiment-analysis", model="stevhliu/my_awesome_model")
+>>> classifier(text)
+[{'label': 'POSITIVE', 'score': 0.9994940757751465}]
+```
+
+원한다면, `pipeline`의 결과를 수동으로 복제할 수도 있습니다.
+
+
+
+텍스트를 토큰화하고 PyTorch 텐서를 반환합니다.
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+```
+
+입력을 모델에 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("stevhliu/my_awesome_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+가장 높은 확률을 가진 클래스를 모델의 `id2label` 매핑을 사용하여 텍스트 레이블로 변환합니다:
+
+```py
+>>> predicted_class_id = logits.argmax().item()
+>>> model.config.id2label[predicted_class_id]
+'POSITIVE'
+```
+
+
+텍스트를 토큰화하고 TensorFlow 텐서를 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+```
+
+입력값을 모델에 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("stevhliu/my_awesome_model")
+>>> logits = model(**inputs).logits
+```
+
+가장 높은 확률을 가진 클래스를 모델의 `id2label` 매핑을 사용하여 텍스트 레이블로 변환합니다:
+
+```py
+>>> predicted_class_id = int(tf.math.argmax(logits, axis=-1)[0])
+>>> model.config.id2label[predicted_class_id]
+'POSITIVE'
+```
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/summarization.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/summarization.md
new file mode 100644
index 0000000000000000000000000000000000000000..a2b2b1fbc95498baaeb02b00b39894d60e801370
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/summarization.md
@@ -0,0 +1,413 @@
+
+
+# 요약[[summarization]]
+
+[[open-in-colab]]
+
+
+
+요약은 문서나 기사에서 중요한 정보를 모두 포함하되 짧게 만드는 일입니다.
+번역과 마찬가지로, 시퀀스-투-시퀀스 문제로 구성할 수 있는 대표적인 작업 중 하나입니다.
+요약에는 아래와 같이 유형이 있습니다:
+
+- 추출(Extractive) 요약: 문서에서 가장 관련성 높은 정보를 추출합니다.
+- 생성(Abstractive) 요약: 가장 관련성 높은 정보를 포착해내는 새로운 텍스트를 생성합니다.
+
+이 가이드에서 소개할 내용은 아래와 같습니다:
+
+1. 생성 요약을 위한 [BillSum](https://huggingface.co/datasets/billsum) 데이터셋 중 캘리포니아 주 법안 하위 집합으로 [T5](https://huggingface.co/google-t5/t5-small)를 파인튜닝합니다.
+2. 파인튜닝된 모델을 사용하여 추론합니다.
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/summarization)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate rouge_score
+```
+
+Hugging Face 계정에 로그인하면 모델을 업로드하고 커뮤니티에 공유할 수 있습니다.
+토큰을 입력하여 로그인하세요.
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## BillSum 데이터셋 가져오기[[load-billsum-dataset]]
+
+🤗 Datasets 라이브러리에서 BillSum 데이터셋의 작은 버전인 캘리포니아 주 법안 하위 집합을 가져오세요:
+
+```py
+>>> from datasets import load_dataset
+
+>>> billsum = load_dataset("billsum", split="ca_test")
+```
+
+[`~datasets.Dataset.train_test_split`] 메소드로 데이터셋을 학습용와 테스트용으로 나누세요:
+
+```py
+>>> billsum = billsum.train_test_split(test_size=0.2)
+```
+
+그런 다음 예시를 하나 살펴보세요:
+
+```py
+>>> billsum["train"][0]
+{'summary': 'Existing law authorizes state agencies to enter into contracts for the acquisition of goods or services upon approval by the Department of General Services. Existing law sets forth various requirements and prohibitions for those contracts, including, but not limited to, a prohibition on entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between spouses and domestic partners or same-sex and different-sex couples in the provision of benefits. Existing law provides that a contract entered into in violation of those requirements and prohibitions is void and authorizes the state or any person acting on behalf of the state to bring a civil action seeking a determination that a contract is in violation and therefore void. Under existing law, a willful violation of those requirements and prohibitions is a misdemeanor.\nThis bill would also prohibit a state agency from entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between employees on the basis of gender identity in the provision of benefits, as specified. By expanding the scope of a crime, this bill would impose a state-mandated local program.\nThe California Constitution requires the state to reimburse local agencies and school districts for certain costs mandated by the state. Statutory provisions establish procedures for making that reimbursement.\nThis bill would provide that no reimbursement is required by this act for a specified reason.',
+ 'text': 'The people of the State of California do enact as follows:\n\n\nSECTION 1.\nSection 10295.35 is added to the Public Contract Code, to read:\n10295.35.\n(a) (1) Notwithstanding any other law, a state agency shall not enter into any contract for the acquisition of goods or services in the amount of one hundred thousand dollars ($100,000) or more with a contractor that, in the provision of benefits, discriminates between employees on the basis of an employee’s or dependent’s actual or perceived gender identity, including, but not limited to, the employee’s or dependent’s identification as transgender.\n(2) For purposes of this section, “contract” includes contracts with a cumulative amount of one hundred thousand dollars ($100,000) or more per contractor in each fiscal year.\n(3) For purposes of this section, an employee health plan is discriminatory if the plan is not consistent with Section 1365.5 of the Health and Safety Code and Section 10140 of the Insurance Code.\n(4) The requirements of this section shall apply only to those portions of a contractor’s operations that occur under any of the following conditions:\n(A) Within the state.\n(B) On real property outside the state if the property is owned by the state or if the state has a right to occupy the property, and if the contractor’s presence at that location is connected to a contract with the state.\n(C) Elsewhere in the United States where work related to a state contract is being performed.\n(b) Contractors shall treat as confidential, to the maximum extent allowed by law or by the requirement of the contractor’s insurance provider, any request by an employee or applicant for employment benefits or any documentation of eligibility for benefits submitted by an employee or applicant for employment.\n(c) After taking all reasonable measures to find a contractor that complies with this section, as determined by the state agency, the requirements of this section may be waived under any of the following circumstances:\n(1) There is only one prospective contractor willing to enter into a specific contract with the state agency.\n(2) The contract is necessary to respond to an emergency, as determined by the state agency, that endangers the public health, welfare, or safety, or the contract is necessary for the provision of essential services, and no entity that complies with the requirements of this section capable of responding to the emergency is immediately available.\n(3) The requirements of this section violate, or are inconsistent with, the terms or conditions of a grant, subvention, or agreement, if the agency has made a good faith attempt to change the terms or conditions of any grant, subvention, or agreement to authorize application of this section.\n(4) The contractor is providing wholesale or bulk water, power, or natural gas, the conveyance or transmission of the same, or ancillary services, as required for ensuring reliable services in accordance with good utility practice, if the purchase of the same cannot practically be accomplished through the standard competitive bidding procedures and the contractor is not providing direct retail services to end users.\n(d) (1) A contractor shall not be deemed to discriminate in the provision of benefits if the contractor, in providing the benefits, pays the actual costs incurred in obtaining the benefit.\n(2) If a contractor is unable to provide a certain benefit, despite taking reasonable measures to do so, the contractor shall not be deemed to discriminate in the provision of benefits.\n(e) (1) Every contract subject to this chapter shall contain a statement by which the contractor certifies that the contractor is in compliance with this section.\n(2) The department or other contracting agency shall enforce this section pursuant to its existing enforcement powers.\n(3) (A) If a contractor falsely certifies that it is in compliance with this section, the contract with that contractor shall be subject to Article 9 (commencing with Section 10420), unless, within a time period specified by the department or other contracting agency, the contractor provides to the department or agency proof that it has complied, or is in the process of complying, with this section.\n(B) The application of the remedies or penalties contained in Article 9 (commencing with Section 10420) to a contract subject to this chapter shall not preclude the application of any existing remedies otherwise available to the department or other contracting agency under its existing enforcement powers.\n(f) Nothing in this section is intended to regulate the contracting practices of any local jurisdiction.\n(g) This section shall be construed so as not to conflict with applicable federal laws, rules, or regulations. In the event that a court or agency of competent jurisdiction holds that federal law, rule, or regulation invalidates any clause, sentence, paragraph, or section of this code or the application thereof to any person or circumstances, it is the intent of the state that the court or agency sever that clause, sentence, paragraph, or section so that the remainder of this section shall remain in effect.\nSEC. 2.\nSection 10295.35 of the Public Contract Code shall not be construed to create any new enforcement authority or responsibility in the Department of General Services or any other contracting agency.\nSEC. 3.\nNo reimbursement is required by this act pursuant to Section 6 of Article XIII\u2009B of the California Constitution because the only costs that may be incurred by a local agency or school district will be incurred because this act creates a new crime or infraction, eliminates a crime or infraction, or changes the penalty for a crime or infraction, within the meaning of Section 17556 of the Government Code, or changes the definition of a crime within the meaning of Section 6 of Article XIII\u2009B of the California Constitution.',
+ 'title': 'An act to add Section 10295.35 to the Public Contract Code, relating to public contracts.'}
+```
+
+여기서 다음 두 개의 필드를 사용하게 됩니다:
+
+- `text`: 모델의 입력이 될 법안 텍스트입니다.
+- `summary`: `text`의 간략한 버전으로 모델의 타겟이 됩니다.
+
+## 전처리[[preprocess]]
+
+다음으로 `text`와 `summary`를 처리하기 위한 T5 토크나이저를 가져옵니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> checkpoint = "google-t5/t5-small"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+```
+
+생성하려는 전처리 함수는 아래 조건을 만족해야 합니다:
+
+1. 입력 앞에 프롬프트를 붙여 T5가 요약 작업임을 인식할 수 있도록 합니다. 여러 NLP 작업을 수행할 수 있는 일부 모델은 특정 작업에 대한 프롬프트가 필요합니다.
+2. 레이블을 토큰화할 때 `text_target` 인수를 사용합니다.
+3. `max_length` 매개변수로 설정된 최대 길이를 넘지 않도록 긴 시퀀스를 잘라냅니다.
+
+```py
+>>> prefix = "summarize: "
+
+
+>>> def preprocess_function(examples):
+... inputs = [prefix + doc for doc in examples["text"]]
+... model_inputs = tokenizer(inputs, max_length=1024, truncation=True)
+
+... labels = tokenizer(text_target=examples["summary"], max_length=128, truncation=True)
+
+... model_inputs["labels"] = labels["input_ids"]
+... return model_inputs
+```
+
+전체 데이터셋에 전처리 함수를 적용하려면 🤗 Datasets의 [`~datasets.Dataset.map`] 메소드를 사용하세요.
+`batched=True`로 설정하여 데이터셋의 여러 요소를 한 번에 처리하면 `map` 함수의 속도를 높일 수 있습니다.
+
+```py
+>>> tokenized_billsum = billsum.map(preprocess_function, batched=True)
+```
+
+이제 [`DataCollatorForSeq2Seq`]를 사용하여 예제 배치를 만드세요.
+전체 데이터셋을 최대 길이로 패딩하는 것보다 배치마다 가장 긴 문장 길이에 맞춰 *동적 패딩*하는 것이 더 효율적입니다.
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint)
+```
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint, return_tensors="tf")
+```
+
+
+
+## 평가[[evaluate]]
+
+학습 중에 평가 지표를 포함하면 모델의 성능을 평가하는 데 도움이 되는 경우가 많습니다.
+🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하면 평가 방법을 빠르게 불러올 수 있습니다.
+이 작업에서는 [ROUGE](https://huggingface.co/spaces/evaluate-metric/rouge) 평가 지표를 가져옵니다.
+(평가 지표를 불러오고 계산하는 방법은 🤗 Evaluate [둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하세요.)
+
+```py
+>>> import evaluate
+
+>>> rouge = evaluate.load("rouge")
+```
+
+그런 다음 예측값과 레이블을 [`~evaluate.EvaluationModule.compute`]에 전달하여 ROUGE 지표를 계산하는 함수를 만듭니다:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... decoded_preds = tokenizer.batch_decode(predictions, skip_special_tokens=True)
+... labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+... decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+... result = rouge.compute(predictions=decoded_preds, references=decoded_labels, use_stemmer=True)
+
+... prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in predictions]
+... result["gen_len"] = np.mean(prediction_lens)
+
+... return {k: round(v, 4) for k, v in result.items()}
+```
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었으며, 학습을 설정할 때 이 함수로 되돌아올 것입니다.
+
+## 학습[[train]]
+
+
+
+
+
+모델을 [`Trainer`]로 파인튜닝 하는 것이 익숙하지 않다면, [여기](../training#train-with-pytorch-trainer)에서 기본 튜토리얼을 확인해보세요!
+
+
+
+이제 모델 학습을 시작할 준비가 되었습니다! [`AutoModelForSeq2SeqLM`]로 T5를 가져오세요:
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM, Seq2SeqTrainingArguments, Seq2SeqTrainer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+이제 세 단계만 남았습니다:
+
+1. [`Seq2SeqTrainingArguments`]에서 학습 하이퍼파라미터를 정의하세요.
+유일한 필수 매개변수는 모델을 저장할 위치를 지정하는 `output_dir`입니다.
+`push_to_hub=True`를 설정하여 이 모델을 Hub에 푸시할 수 있습니다(모델을 업로드하려면 Hugging Face에 로그인해야 합니다.)
+[`Trainer`]는 각 에폭이 끝날 때마다 ROUGE 지표를 평가하고 학습 체크포인트를 저장합니다.
+2. 모델, 데이터셋, 토크나이저, 데이터 콜레이터 및 `compute_metrics` 함수와 함께 학습 인수를 [`Seq2SeqTrainer`]에 전달하세요.
+3. [`~Trainer.train`]을 호출하여 모델을 파인튜닝하세요.
+
+```py
+>>> training_args = Seq2SeqTrainingArguments(
+... output_dir="my_awesome_billsum_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... weight_decay=0.01,
+... save_total_limit=3,
+... num_train_epochs=4,
+... predict_with_generate=True,
+... fp16=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Seq2SeqTrainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_billsum["train"],
+... eval_dataset=tokenized_billsum["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+학습이 완료되면, 누구나 모델을 사용할 수 있도록 [`~transformers.Trainer.push_to_hub`] 메소드로 Hub에 공유합니다:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras로 모델 파인튜닝을 하는 것이 익숙하지 않다면, [여기](../training#train-a-tensorflow-model-with-keras)에서 기본적인 튜토리얼을 확인하세요!
+
+
+TensorFlow에서 모델을 파인튜닝하려면, 먼저 옵티마이저, 학습률 스케줄 그리고 몇 가지 학습 하이퍼파라미터를 설정하세요:
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+그런 다음 [`TFAutoModelForSeq2SeqLM`]을 사용하여 T5를 가져오세요:
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]을 사용하여 데이터셋을 `tf.data.Dataset` 형식으로 변환하세요:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_billsum["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... tokenized_billsum["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)을 사용하여 모델을 학습할 수 있도록 구성하세요:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+학습을 시작하기 전에 설정해야 할 마지막 두 가지는 예측에서 ROUGE 점수를 계산하고 모델을 Hub에 푸시하는 방법을 제공하는 것입니다.
+두 작업 모두 [Keras callbacks](../main_classes/keras_callbacks)으로 수행할 수 있습니다.
+
+[`~transformers.KerasMetricCallback`]에 `compute_metrics` 함수를 전달하세요:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+[`~transformers.PushToHubCallback`]에서 모델과 토크나이저를 푸시할 위치를 지정하세요:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_billsum_model",
+... tokenizer=tokenizer,
+... )
+```
+
+그런 다음 콜백을 번들로 묶어줍니다:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+드디어 모델 학습을 시작할 준비가 되었습니다!
+학습 및 검증 데이터셋, 에폭 수 및 콜백과 함께 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)을 호출하여 모델을 파인튜닝하세요.
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=callbacks)
+```
+
+학습이 완료되면 모델이 자동으로 Hub에 업로드되어 누구나 사용할 수 있게 됩니다!
+
+
+
+
+
+요약을 위해 모델을 파인튜닝하는 방법에 대한 더 자세한 예제를 보려면 [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization.ipynb)
+또는 [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization-tf.ipynb)을 참고하세요.
+
+
+
+## 추론[[inference]]
+
+좋아요, 이제 모델을 파인튜닝했으니 추론에 사용할 수 있습니다!
+
+요약할 텍스트를 작성해보세요. T5의 경우 작업에 따라 입력 앞에 접두사를 붙여야 합니다. 요약의 경우, 아래와 같은 접두사를 입력 앞에 붙여야 합니다:
+
+```py
+>>> text = "summarize: The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country. It'll lower the deficit and ask the ultra-wealthy and corporations to pay their fair share. And no one making under $400,000 per year will pay a penny more in taxes."
+```
+
+추론을 위해 파인튜닝한 모델을 시험해 보는 가장 간단한 방법은 [`pipeline`]에서 사용하는 것입니다.
+모델을 사용하여 요약을 수행할 [`pipeline`]을 인스턴스화하고 텍스트를 전달하세요:
+
+```py
+>>> from transformers import pipeline
+
+>>> summarizer = pipeline("summarization", model="stevhliu/my_awesome_billsum_model")
+>>> summarizer(text)
+[{"summary_text": "The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country."}]
+```
+
+원한다면 수동으로 다음과 같은 작업을 수행하여 [`pipeline`]의 결과와 동일한 결과를 얻을 수 있습니다:
+
+
+
+
+텍스트를 토크나이즈하고 `input_ids`를 PyTorch 텐서로 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> inputs = tokenizer(text, return_tensors="pt").input_ids
+```
+
+요약문을 생성하려면 [`~generation.GenerationMixin.generate`] 메소드를 사용하세요.
+텍스트 생성에 대한 다양한 전략과 생성을 제어하기 위한 매개변수에 대한 자세한 내용은 [텍스트 생성](../main_classes/text_generation) API를 참조하세요.
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
+```
+
+생성된 토큰 ID를 텍스트로 디코딩합니다:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
+```
+
+
+텍스트를 토크나이즈하고 `input_ids`를 TensorFlow 텐서로 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> inputs = tokenizer(text, return_tensors="tf").input_ids
+```
+
+요약문을 생성하려면 [`~transformers.generation_tf_utils.TFGenerationMixin.generate`] 메소드를 사용하세요.
+텍스트 생성에 대한 다양한 전략과 생성을 제어하기 위한 매개변수에 대한 자세한 내용은 [텍스트 생성](../main_classes/text_generation) API를 참조하세요.
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained("stevhliu/my_awesome_billsum_model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
+```
+
+생성된 토큰 ID를 텍스트로 디코딩합니다:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
+```
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/token_classification.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/token_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..a65503092cee1decc8e2983ba4df1bf5e1db6921
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/token_classification.md
@@ -0,0 +1,555 @@
+
+
+# 토큰 분류[[token-classification]]
+
+[[open-in-colab]]
+
+
+
+토큰 분류는 문장의 개별 토큰에 레이블을 할당합니다. 가장 일반적인 토큰 분류 작업 중 하나는 개체명 인식(Named Entity Recognition, NER)입니다. 개체명 인식은 문장에서 사람, 위치 또는 조직과 같은 각 개체의 레이블을 찾으려고 시도합니다.
+
+이 가이드에서 학습할 내용은:
+
+1. [WNUT 17](https://huggingface.co/datasets/wnut_17) 데이터 세트에서 [DistilBERT](https://huggingface.co/distilbert/distilbert-base-uncased)를 파인 튜닝하여 새로운 개체를 탐지합니다.
+2. 추론을 위해 파인 튜닝 모델을 사용합니다.
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/token-classification)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에, 필요한 모든 라이브러리가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate seqeval
+```
+
+Hugging Face 계정에 로그인하여 모델을 업로드하고 커뮤니티에 공유하는 것을 권장합니다. 메시지가 표시되면, 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## WNUT 17 데이터 세트 가져오기[[load-wnut-17-dataset]]
+
+먼저 🤗 Datasets 라이브러리에서 WNUT 17 데이터 세트를 가져옵니다:
+
+```py
+>>> from datasets import load_dataset
+
+>>> wnut = load_dataset("wnut_17")
+```
+
+다음 예제를 살펴보세요:
+
+```py
+>>> wnut["train"][0]
+{'id': '0',
+ 'ner_tags': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 7, 8, 8, 0, 7, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'tokens': ['@paulwalk', 'It', "'s", 'the', 'view', 'from', 'where', 'I', "'m", 'living', 'for', 'two', 'weeks', '.', 'Empire', 'State', 'Building', '=', 'ESB', '.', 'Pretty', 'bad', 'storm', 'here', 'last', 'evening', '.']
+}
+```
+
+`ner_tags`의 각 숫자는 개체를 나타냅니다. 숫자를 레이블 이름으로 변환하여 개체가 무엇인지 확인합니다:
+
+```py
+>>> label_list = wnut["train"].features[f"ner_tags"].feature.names
+>>> label_list
+[
+ "O",
+ "B-corporation",
+ "I-corporation",
+ "B-creative-work",
+ "I-creative-work",
+ "B-group",
+ "I-group",
+ "B-location",
+ "I-location",
+ "B-person",
+ "I-person",
+ "B-product",
+ "I-product",
+]
+```
+
+각 `ner_tag`의 앞에 붙은 문자는 개체의 토큰 위치를 나타냅니다:
+
+- `B-`는 개체의 시작을 나타냅니다.
+- `I-`는 토큰이 동일한 개체 내부에 포함되어 있음을 나타냅니다(예를 들어 `State` 토큰은 `Empire State Building`와 같은 개체의 일부입니다).
+- `0`는 토큰이 어떤 개체에도 해당하지 않음을 나타냅니다.
+
+## 전처리[[preprocess]]
+
+
+
+다음으로 `tokens` 필드를 전처리하기 위해 DistilBERT 토크나이저를 가져옵니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+위의 예제 `tokens` 필드를 보면 입력이 이미 토큰화된 것처럼 보입니다. 그러나 실제로 입력은 아직 토큰화되지 않았으므로 단어를 하위 단어로 토큰화하기 위해 `is_split_into_words=True`를 설정해야 합니다. 예제로 확인합니다:
+
+```py
+>>> example = wnut["train"][0]
+>>> tokenized_input = tokenizer(example["tokens"], is_split_into_words=True)
+>>> tokens = tokenizer.convert_ids_to_tokens(tokenized_input["input_ids"])
+>>> tokens
+['[CLS]', '@', 'paul', '##walk', 'it', "'", 's', 'the', 'view', 'from', 'where', 'i', "'", 'm', 'living', 'for', 'two', 'weeks', '.', 'empire', 'state', 'building', '=', 'es', '##b', '.', 'pretty', 'bad', 'storm', 'here', 'last', 'evening', '.', '[SEP]']
+```
+
+그러나 이로 인해 `[CLS]`과 `[SEP]`라는 특수 토큰이 추가되고, 하위 단어 토큰화로 인해 입력과 레이블 간에 불일치가 발생합니다. 하나의 레이블에 해당하는 단일 단어는 이제 두 개의 하위 단어로 분할될 수 있습니다. 토큰과 레이블을 다음과 같이 재정렬해야 합니다:
+
+1. [`word_ids`](https://huggingface.co/docs/transformers/main_classes/tokenizer#transformers.BatchEncoding.word_ids) 메소드로 모든 토큰을 해당 단어에 매핑합니다.
+2. 특수 토큰 `[CLS]`와 `[SEP]`에 `-100` 레이블을 할당하여, PyTorch 손실 함수가 해당 토큰을 무시하도록 합니다.
+3. 주어진 단어의 첫 번째 토큰에만 레이블을 지정합니다. 같은 단어의 다른 하위 토큰에 `-100`을 할당합니다.
+
+다음은 토큰과 레이블을 재정렬하고 DistilBERT의 최대 입력 길이보다 길지 않도록 시퀀스를 잘라내는 함수를 만드는 방법입니다:
+
+```py
+>>> def tokenize_and_align_labels(examples):
+... tokenized_inputs = tokenizer(examples["tokens"], truncation=True, is_split_into_words=True)
+
+... labels = []
+... for i, label in enumerate(examples[f"ner_tags"]):
+... word_ids = tokenized_inputs.word_ids(batch_index=i) # Map tokens to their respective word.
+... previous_word_idx = None
+... label_ids = []
+... for word_idx in word_ids: # Set the special tokens to -100.
+... if word_idx is None:
+... label_ids.append(-100)
+... elif word_idx != previous_word_idx: # Only label the first token of a given word.
+... label_ids.append(label[word_idx])
+... else:
+... label_ids.append(-100)
+... previous_word_idx = word_idx
+... labels.append(label_ids)
+
+... tokenized_inputs["labels"] = labels
+... return tokenized_inputs
+```
+
+전체 데이터 세트에 전처리 함수를 적용하려면, 🤗 Datasets [`~datasets.Dataset.map`] 함수를 사용하세요. `batched=True`로 설정하여 데이터 세트의 여러 요소를 한 번에 처리하면 `map` 함수의 속도를 높일 수 있습니다:
+```py
+>>> tokenized_wnut = wnut.map(tokenize_and_align_labels, batched=True)
+```
+
+이제 [`DataCollatorWithPadding`]를 사용하여 예제 배치를 만들어봅시다. 데이터 세트 전체를 최대 길이로 패딩하는 대신, *동적 패딩*을 사용하여 배치에서 가장 긴 길이에 맞게 문장을 패딩하는 것이 효율적입니다.
+
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer)
+```
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer, return_tensors="tf")
+```
+
+
+
+## 평가[[evaluation]]
+
+훈련 중 모델의 성능을 평가하기 위해 평가 지표를 포함하는 것이 유용합니다. 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리를 사용하여 빠르게 평가 방법을 가져올 수 있습니다. 이 작업에서는 [seqeval](https://huggingface.co/spaces/evaluate-metric/seqeval) 평가 지표를 가져옵니다. (평가 지표를 가져오고 계산하는 방법에 대해서는 🤗 Evaluate [빠른 둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하세요). Seqeval은 실제로 정밀도, 재현률, F1 및 정확도와 같은 여러 점수를 산출합니다.
+
+```py
+>>> import evaluate
+
+>>> seqeval = evaluate.load("seqeval")
+```
+
+먼저 NER 레이블을 가져온 다음, [`~evaluate.EvaluationModule.compute`]에 실제 예측과 실제 레이블을 전달하여 점수를 계산하는 함수를 만듭니다:
+
+```py
+>>> import numpy as np
+
+>>> labels = [label_list[i] for i in example[f"ner_tags"]]
+
+
+>>> def compute_metrics(p):
+... predictions, labels = p
+... predictions = np.argmax(predictions, axis=2)
+
+... true_predictions = [
+... [label_list[p] for (p, l) in zip(prediction, label) if l != -100]
+... for prediction, label in zip(predictions, labels)
+... ]
+... true_labels = [
+... [label_list[l] for (p, l) in zip(prediction, label) if l != -100]
+... for prediction, label in zip(predictions, labels)
+... ]
+
+... results = seqeval.compute(predictions=true_predictions, references=true_labels)
+... return {
+... "precision": results["overall_precision"],
+... "recall": results["overall_recall"],
+... "f1": results["overall_f1"],
+... "accuracy": results["overall_accuracy"],
+... }
+```
+
+이제 `compute_metrics` 함수를 사용할 준비가 되었으며, 훈련을 설정하면 이 함수로 되돌아올 것입니다.
+
+## 훈련[[train]]
+
+모델을 훈련하기 전에, `id2label`와 `label2id`를 사용하여 예상되는 id와 레이블의 맵을 생성하세요:
+
+```py
+>>> id2label = {
+... 0: "O",
+... 1: "B-corporation",
+... 2: "I-corporation",
+... 3: "B-creative-work",
+... 4: "I-creative-work",
+... 5: "B-group",
+... 6: "I-group",
+... 7: "B-location",
+... 8: "I-location",
+... 9: "B-person",
+... 10: "I-person",
+... 11: "B-product",
+... 12: "I-product",
+... }
+>>> label2id = {
+... "O": 0,
+... "B-corporation": 1,
+... "I-corporation": 2,
+... "B-creative-work": 3,
+... "I-creative-work": 4,
+... "B-group": 5,
+... "I-group": 6,
+... "B-location": 7,
+... "I-location": 8,
+... "B-person": 9,
+... "I-person": 10,
+... "B-product": 11,
+... "I-product": 12,
+... }
+```
+
+
+
+
+
+[`Trainer`]를 사용하여 모델을 파인 튜닝하는 방법에 익숙하지 않은 경우, [여기](../training#train-with-pytorch-trainer)에서 기본 튜토리얼을 확인하세요!
+
+
+
+이제 모델을 훈련시킬 준비가 되었습니다! [`AutoModelForSequenceClassification`]로 DistilBERT를 가져오고 예상되는 레이블 수와 레이블 매핑을 지정하세요:
+
+```py
+>>> from transformers import AutoModelForTokenClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForTokenClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=13, id2label=id2label, label2id=label2id
+... )
+```
+
+이제 세 단계만 거치면 끝입니다:
+
+1. [`TrainingArguments`]에서 하이퍼파라미터를 정의하세요. `output_dir`는 모델을 저장할 위치를 지정하는 유일한 매개변수입니다. 이 모델을 허브에 업로드하기 위해 `push_to_hub=True`를 설정합니다(모델을 업로드하기 위해 Hugging Face에 로그인해야합니다.) 각 에폭이 끝날 때마다, [`Trainer`]는 seqeval 점수를 평가하고 훈련 체크포인트를 저장합니다.
+2. [`Trainer`]에 훈련 인수와 모델, 데이터 세트, 토크나이저, 데이터 콜레이터 및 `compute_metrics` 함수를 전달하세요.
+3. [`~Trainer.train`]를 호출하여 모델을 파인 튜닝하세요.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_wnut_model",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=2,
+... weight_decay=0.01,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... load_best_model_at_end=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_wnut["train"],
+... eval_dataset=tokenized_wnut["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+훈련이 완료되면, [`~transformers.Trainer.push_to_hub`] 메소드를 사용하여 모델을 허브에 공유할 수 있습니다.
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras를 사용하여 모델을 파인 튜닝하는 방법에 익숙하지 않은 경우, [여기](../training#train-a-tensorflow-model-with-keras)의 기본 튜토리얼을 확인하세요!
+
+
+TensorFlow에서 모델을 파인 튜닝하려면, 먼저 옵티마이저 함수와 학습률 스케쥴, 그리고 일부 훈련 하이퍼파라미터를 설정해야 합니다:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_train_epochs = 3
+>>> num_train_steps = (len(tokenized_wnut["train"]) // batch_size) * num_train_epochs
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=2e-5,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=0.01,
+... num_warmup_steps=0,
+... )
+```
+
+그런 다음 [`TFAutoModelForSequenceClassification`]을 사용하여 DistilBERT를 가져오고, 예상되는 레이블 수와 레이블 매핑을 지정합니다:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=13, id2label=id2label, label2id=label2id
+... )
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]을 사용하여 데이터 세트를 `tf.data.Dataset` 형식으로 변환합니다:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_wnut["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_wnut["validation"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+[`compile`](https://keras.io/api/models/model_training_apis/#compile-method)를 사용하여 훈련할 모델을 구성합니다:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+훈련을 시작하기 전에 설정해야할 마지막 두 가지는 예측에서 seqeval 점수를 계산하고, 모델을 허브에 업로드할 방법을 제공하는 것입니다. 모두 [Keras callbacks](../main_classes/keras_callbacks)를 사용하여 수행됩니다.
+
+[`~transformers.KerasMetricCallback`]에 `compute_metrics` 함수를 전달하세요:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+[`~transformers.PushToHubCallback`]에서 모델과 토크나이저를 업로드할 위치를 지정합니다:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_wnut_model",
+... tokenizer=tokenizer,
+... )
+```
+
+그런 다음 콜백을 함께 묶습니다:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+드디어, 모델 훈련을 시작할 준비가 되었습니다! [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)에 훈련 데이터 세트, 검증 데이터 세트, 에폭의 수 및 콜백을 전달하여 파인 튜닝합니다:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=callbacks)
+```
+
+훈련이 완료되면, 모델이 자동으로 허브에 업로드되어 누구나 사용할 수 있습니다!
+
+
+
+
+
+토큰 분류를 위한 모델을 파인 튜닝하는 자세한 예제는 다음
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb)
+또는 [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification-tf.ipynb)를 참조하세요.
+
+
+
+## 추론[[inference]]
+
+좋아요, 이제 모델을 파인 튜닝했으니 추론에 사용할 수 있습니다!
+
+추론을 수행하고자 하는 텍스트를 가져와봅시다:
+
+```py
+>>> text = "The Golden State Warriors are an American professional basketball team based in San Francisco."
+```
+
+파인 튜닝된 모델로 추론을 시도하는 가장 간단한 방법은 [`pipeline`]를 사용하는 것입니다. 모델로 NER의 `pipeline`을 인스턴스화하고, 텍스트를 전달해보세요:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("ner", model="stevhliu/my_awesome_wnut_model")
+>>> classifier(text)
+[{'entity': 'B-location',
+ 'score': 0.42658573,
+ 'index': 2,
+ 'word': 'golden',
+ 'start': 4,
+ 'end': 10},
+ {'entity': 'I-location',
+ 'score': 0.35856336,
+ 'index': 3,
+ 'word': 'state',
+ 'start': 11,
+ 'end': 16},
+ {'entity': 'B-group',
+ 'score': 0.3064001,
+ 'index': 4,
+ 'word': 'warriors',
+ 'start': 17,
+ 'end': 25},
+ {'entity': 'B-location',
+ 'score': 0.65523505,
+ 'index': 13,
+ 'word': 'san',
+ 'start': 80,
+ 'end': 83},
+ {'entity': 'B-location',
+ 'score': 0.4668663,
+ 'index': 14,
+ 'word': 'francisco',
+ 'start': 84,
+ 'end': 93}]
+```
+
+원한다면, `pipeline`의 결과를 수동으로 복제할 수도 있습니다:
+
+
+
+텍스트를 토큰화하고 PyTorch 텐서를 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+```
+
+입력을 모델에 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import AutoModelForTokenClassification
+
+>>> model = AutoModelForTokenClassification.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+가장 높은 확률을 가진 클래스를 모델의 `id2label` 매핑을 사용하여 텍스트 레이블로 변환합니다:
+
+```py
+>>> predictions = torch.argmax(logits, dim=2)
+>>> predicted_token_class = [model.config.id2label[t.item()] for t in predictions[0]]
+>>> predicted_token_class
+['O',
+ 'O',
+ 'B-location',
+ 'I-location',
+ 'B-group',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'B-location',
+ 'B-location',
+ 'O',
+ 'O']
+```
+
+
+텍스트를 토큰화하고 TensorFlow 텐서를 반환합니다:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+```
+
+입력값을 모델에 전달하고 `logits`을 반환합니다:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> logits = model(**inputs).logits
+```
+
+가장 높은 확률을 가진 클래스를 모델의 `id2label` 매핑을 사용하여 텍스트 레이블로 변환합니다:
+
+```py
+>>> predicted_token_class_ids = tf.math.argmax(logits, axis=-1)
+>>> predicted_token_class = [model.config.id2label[t] for t in predicted_token_class_ids[0].numpy().tolist()]
+>>> predicted_token_class
+['O',
+ 'O',
+ 'B-location',
+ 'I-location',
+ 'B-group',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'B-location',
+ 'B-location',
+ 'O',
+ 'O']
+```
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/translation.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/translation.md
new file mode 100644
index 0000000000000000000000000000000000000000..5b4eaaa6125a11b0167be3c45d8cc1d021846ec0
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/translation.md
@@ -0,0 +1,407 @@
+
+
+# 번역[[translation]]
+
+[[open-in-colab]]
+
+
+
+번역은 한 언어로 된 시퀀스를 다른 언어로 변환합니다. 번역이나 요약은 입력을 받아 일련의 출력을 반환하는 강력한 프레임워크인 시퀀스-투-시퀀스 문제로 구성할 수 있는 대표적인 태스크입니다. 번역 시스템은 일반적으로 다른 언어로 된 텍스트 간의 번역에 사용되지만, 음성 간의 통역이나 텍스트-음성 또는 음성-텍스트와 같은 조합에도 사용될 수 있습니다.
+
+이 가이드에서 학습할 내용은:
+
+1. 영어 텍스트를 프랑스어로 번역하기 위해 [T5](https://huggingface.co/google-t5/t5-small) 모델을 OPUS Books 데이터세트의 영어-프랑스어 하위 집합으로 파인튜닝하는 방법과
+2. 파인튜닝된 모델을 추론에 사용하는 방법입니다.
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/translation)를 확인하는 것이 좋습니다.
+
+
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers datasets evaluate sacrebleu
+```
+
+모델을 업로드하고 커뮤니티와 공유할 수 있도록 Hugging Face 계정에 로그인하는 것이 좋습니다. 새로운 창이 표시되면 토큰을 입력하여 로그인하세요.
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## OPUS Books 데이터세트 가져오기[[load-opus-books-dataset]]
+
+먼저 🤗 Datasets 라이브러리에서 [OPUS Books](https://huggingface.co/datasets/opus_books) 데이터세트의 영어-프랑스어 하위 집합을 가져오세요.
+
+```py
+>>> from datasets import load_dataset
+
+>>> books = load_dataset("opus_books", "en-fr")
+```
+
+데이터세트를 [`~datasets.Dataset.train_test_split`] 메서드를 사용하여 훈련 및 테스트 데이터로 분할하세요.
+
+```py
+>>> books = books["train"].train_test_split(test_size=0.2)
+```
+
+훈련 데이터에서 예시를 살펴볼까요?
+
+```py
+>>> books["train"][0]
+{'id': '90560',
+ 'translation': {'en': 'But this lofty plateau measured only a few fathoms, and soon we reentered Our Element.',
+ 'fr': 'Mais ce plateau élevé ne mesurait que quelques toises, et bientôt nous fûmes rentrés dans notre élément.'}}
+```
+
+반환된 딕셔너리의 `translation` 키가 텍스트의 영어, 프랑스어 버전을 포함하고 있는 것을 볼 수 있습니다.
+
+## 전처리[[preprocess]]
+
+
+
+다음 단계로 영어-프랑스어 쌍을 처리하기 위해 T5 토크나이저를 가져오세요.
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> checkpoint = "google-t5/t5-small"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+```
+
+만들 전처리 함수는 아래 요구사항을 충족해야 합니다:
+
+1. T5가 번역 태스크임을 인지할 수 있도록 입력 앞에 프롬프트를 추가하세요. 여러 NLP 태스크를 할 수 있는 모델 중 일부는 이렇게 태스크 프롬프트를 미리 줘야합니다.
+2. 원어(영어)과 번역어(프랑스어)를 별도로 토큰화하세요. 영어 어휘로 사전 학습된 토크나이저로 프랑스어 텍스트를 토큰화할 수는 없기 때문입니다.
+3. `max_length` 매개변수로 설정한 최대 길이보다 길지 않도록 시퀀스를 truncate하세요.
+
+```py
+>>> source_lang = "en"
+>>> target_lang = "fr"
+>>> prefix = "translate English to French: "
+
+
+>>> def preprocess_function(examples):
+... inputs = [prefix + example[source_lang] for example in examples["translation"]]
+... targets = [example[target_lang] for example in examples["translation"]]
+... model_inputs = tokenizer(inputs, text_target=targets, max_length=128, truncation=True)
+... return model_inputs
+```
+
+전체 데이터세트에 전처리 함수를 적용하려면 🤗 Datasets의 [`~datasets.Dataset.map`] 메서드를 사용하세요. `map` 함수의 속도를 높이려면 `batched=True`를 설정하여 데이터세트의 여러 요소를 한 번에 처리하는 방법이 있습니다.
+
+```py
+>>> tokenized_books = books.map(preprocess_function, batched=True)
+```
+
+이제 [`DataCollatorForSeq2Seq`]를 사용하여 예제 배치를 생성합니다. 데이터세트의 최대 길이로 전부를 padding하는 대신, 데이터 정렬 중 각 배치의 최대 길이로 문장을 *동적으로 padding*하는 것이 더 효율적입니다.
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint)
+```
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint, return_tensors="tf")
+```
+
+
+
+## 평가[[evalulate]]
+
+훈련 중에 메트릭을 포함하면 모델의 성능을 평가하는 데 도움이 됩니다. 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리로 평가 방법(evaluation method)을 빠르게 가져올 수 있습니다. 현재 태스크에 적합한 SacreBLEU 메트릭을 가져오세요. (메트릭을 가져오고 계산하는 방법에 대해 자세히 알아보려면 🤗 Evaluate [둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하세요):
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("sacrebleu")
+```
+
+그런 다음 [`~evaluate.EvaluationModule.compute`]에 예측값과 레이블을 전달하여 SacreBLEU 점수를 계산하는 함수를 생성하세요:
+
+```py
+>>> import numpy as np
+
+
+>>> def postprocess_text(preds, labels):
+... preds = [pred.strip() for pred in preds]
+... labels = [[label.strip()] for label in labels]
+
+... return preds, labels
+
+
+>>> def compute_metrics(eval_preds):
+... preds, labels = eval_preds
+... if isinstance(preds, tuple):
+... preds = preds[0]
+... decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
+
+... labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+... decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+... decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
+
+... result = metric.compute(predictions=decoded_preds, references=decoded_labels)
+... result = {"bleu": result["score"]}
+
+... prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in preds]
+... result["gen_len"] = np.mean(prediction_lens)
+... result = {k: round(v, 4) for k, v in result.items()}
+... return result
+```
+
+이제 `compute_metrics` 함수는 준비되었고, 훈련 과정을 설정할 때 다시 살펴볼 예정입니다.
+
+## 훈련[[train]]
+
+
+
+
+
+[`Trainer`]로 모델을 파인튜닝하는 방법에 익숙하지 않다면 [여기](../training#train-with-pytorch-trainer)에서 기본 튜토리얼을 살펴보시기 바랍니다!
+
+
+
+모델을 훈련시킬 준비가 되었군요! [`AutoModelForSeq2SeqLM`]으로 T5를 로드하세요:
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM, Seq2SeqTrainingArguments, Seq2SeqTrainer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+이제 세 단계만 거치면 끝입니다:
+
+1. [`Seq2SeqTrainingArguments`]에서 훈련 하이퍼파라미터를 정의하세요. 유일한 필수 매개변수는 모델을 저장할 위치인 `output_dir`입니다. 모델을 Hub에 푸시하기 위해 `push_to_hub=True`로 설정하세요. (모델을 업로드하려면 Hugging Face에 로그인해야 합니다.) [`Trainer`]는 에폭이 끝날때마다 SacreBLEU 메트릭을 평가하고 훈련 체크포인트를 저장합니다.
+2. [`Seq2SeqTrainer`]에 훈련 인수를 전달하세요. 모델, 데이터 세트, 토크나이저, data collator 및 `compute_metrics` 함수도 덩달아 전달해야 합니다.
+3. [`~Trainer.train`]을 호출하여 모델을 파인튜닝하세요.
+
+```py
+>>> training_args = Seq2SeqTrainingArguments(
+... output_dir="my_awesome_opus_books_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... weight_decay=0.01,
+... save_total_limit=3,
+... num_train_epochs=2,
+... predict_with_generate=True,
+... fp16=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Seq2SeqTrainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_books["train"],
+... eval_dataset=tokenized_books["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+학습이 완료되면 [`~transformers.Trainer.push_to_hub`] 메서드로 모델을 Hub에 공유하세요. 이러면 누구나 모델을 사용할 수 있게 됩니다:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+Keras로 모델을 파인튜닝하는 방법이 익숙하지 않다면, [여기](../training#train-a-tensorflow-model-with-keras)에서 기본 튜토리얼을 살펴보시기 바랍니다!
+
+
+TensorFlow에서 모델을 파인튜닝하려면 우선 optimizer 함수, 학습률 스케줄 등의 훈련 하이퍼파라미터를 설정하세요:
+
+```py
+>>> from transformers import AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+이제 [`TFAutoModelForSeq2SeqLM`]로 T5를 가져오세요:
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+[`~transformers.TFPreTrainedModel.prepare_tf_dataset`]로 데이터 세트를 `tf.data.Dataset` 형식으로 변환하세요:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_books["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... tokenized_books["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+훈련하기 위해 [`compile`](https://keras.io/api/models/model_training_apis/#compile-method) 메서드로 모델을 구성하세요:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+훈련을 시작하기 전에 예측값으로부터 SacreBLEU 메트릭을 계산하는 방법과 모델을 Hub에 업로드하는 방법 두 가지를 미리 설정해둬야 합니다. 둘 다 [Keras callbacks](../main_classes/keras_callbacks)로 구현하세요.
+
+[`~transformers.KerasMetricCallback`]에 `compute_metrics` 함수를 전달하세요.
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+모델과 토크나이저를 업로드할 위치를 [`~transformers.PushToHubCallback`]에서 지정하세요:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_opus_books_model",
+... tokenizer=tokenizer,
+... )
+```
+
+이제 콜백들을 한데로 묶어주세요:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+드디어 모델을 훈련시킬 모든 준비를 마쳤군요! 이제 훈련 및 검증 데이터 세트에 [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) 메서드를 에폭 수와 만들어둔 콜백과 함께 호출하여 모델을 파인튜닝하세요:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=callbacks)
+```
+
+학습이 완료되면 모델이 자동으로 Hub에 업로드되고, 누구나 사용할 수 있게 됩니다!
+
+
+
+
+
+번역을 위해 모델을 파인튜닝하는 방법에 대한 보다 자세한 예제는 해당 [PyTorch 노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation.ipynb) 또는 [TensorFlow 노트북](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation-tf.ipynb)을 참조하세요.
+
+
+
+## 추론[[inference]]
+
+좋아요, 이제 모델을 파인튜닝했으니 추론에 사용할 수 있습니다!
+
+다른 언어로 번역하고 싶은 텍스트를 써보세요. T5의 경우 원하는 태스크를 입력의 접두사로 추가해야 합니다. 예를 들어 영어에서 프랑스어로 번역하는 경우, 아래와 같은 접두사가 추가됩니다:
+
+```py
+>>> text = "translate English to French: Legumes share resources with nitrogen-fixing bacteria."
+```
+
+파인튜닝된 모델로 추론하기에 제일 간단한 방법은 [`pipeline`]을 사용하는 것입니다. 해당 모델로 번역 `pipeline`을 만든 뒤, 텍스트를 전달하세요:
+
+```py
+>>> from transformers import pipeline
+
+# Change `xx` to the language of the input and `yy` to the language of the desired output.
+# Examples: "en" for English, "fr" for French, "de" for German, "es" for Spanish, "zh" for Chinese, etc; translation_en_to_fr translates English to French
+# You can view all the lists of languages here - https://huggingface.co/languages
+>>> translator = pipeline("translation_xx_to_yy", model="my_awesome_opus_books_model")
+>>> translator(text)
+[{'translation_text': 'Legumes partagent des ressources avec des bactéries azotantes.'}]
+```
+
+원한다면 `pipeline`의 결과를 직접 복제할 수도 있습니다:
+
+
+
+텍스트를 토큰화하고 `input_ids`를 PyTorch 텐서로 반환하세요:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_opus_books_model")
+>>> inputs = tokenizer(text, return_tensors="pt").input_ids
+```
+
+[`~generation.GenerationMixin.generate`] 메서드로 번역을 생성하세요. 다양한 텍스트 생성 전략 및 생성을 제어하기 위한 매개변수에 대한 자세한 내용은 [Text Generation](../main_classes/text_generation) API를 살펴보시기 바랍니다.
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("my_awesome_opus_books_model")
+>>> outputs = model.generate(inputs, max_new_tokens=40, do_sample=True, top_k=30, top_p=0.95)
+```
+
+생성된 토큰 ID들을 다시 텍스트로 디코딩하세요:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'Les lignées partagent des ressources avec des bactéries enfixant l'azote.'
+```
+
+
+텍스트를 토큰화하고 `input_ids`를 TensorFlow 텐서로 반환하세요:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_opus_books_model")
+>>> inputs = tokenizer(text, return_tensors="tf").input_ids
+```
+
+[`~transformers.generation_tf_utils.TFGenerationMixin.generate`] 메서드로 번역을 생성하세요. 다양한 텍스트 생성 전략 및 생성을 제어하기 위한 매개변수에 대한 자세한 내용은 [Text Generation](../main_classes/text_generation) API를 살펴보시기 바랍니다.
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained("my_awesome_opus_books_model")
+>>> outputs = model.generate(inputs, max_new_tokens=40, do_sample=True, top_k=30, top_p=0.95)
+```
+
+생성된 토큰 ID들을 다시 텍스트로 디코딩하세요:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'Les lugumes partagent les ressources avec des bactéries fixatrices d'azote.'
+```
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/video_classification.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/video_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..10569083c09f85f6db4e81f88bf78d73742a4702
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/video_classification.md
@@ -0,0 +1,492 @@
+
+
+# 영상 분류 [[video-classification]]
+
+[[open-in-colab]]
+
+
+영상 분류는 영상 전체에 레이블 또는 클래스를 지정하는 작업입니다. 각 영상에는 하나의 클래스가 있을 것으로 예상됩니다. 영상 분류 모델은 영상을 입력으로 받아 어느 클래스에 속하는지에 대한 예측을 반환합니다. 이러한 모델은 영상이 어떤 내용인지 분류하는 데 사용될 수 있습니다. 영상 분류의 실제 응용 예는 피트니스 앱에서 유용한 동작 / 운동 인식 서비스가 있습니다. 이는 또한 시각 장애인이 이동할 때 보조하는데 사용될 수 있습니다
+
+이 가이드에서는 다음을 수행하는 방법을 보여줍니다:
+
+1. [UCF101](https://www.crcv.ucf.edu/data/UCF101.php) 데이터 세트의 하위 집합을 통해 [VideoMAE](https://huggingface.co/docs/transformers/main/en/model_doc/videomae) 모델을 미세 조정하기.
+2. 미세 조정한 모델을 추론에 사용하기.
+
+
+
+이 작업과 호환되는 모든 아키텍처와 체크포인트를 보려면 [작업 페이지](https://huggingface.co/tasks/video-classification)를 확인하는 것이 좋습니다.
+
+
+
+
+시작하기 전에 필요한 모든 라이브러리가 설치되었는지 확인하세요:
+```bash
+pip install -q pytorchvideo transformers evaluate
+```
+
+영상을 처리하고 준비하기 위해 [PyTorchVideo](https://pytorchvideo.org/)(이하 `pytorchvideo`)를 사용합니다.
+
+커뮤니티에 모델을 업로드하고 공유할 수 있도록 Hugging Face 계정에 로그인하는 것을 권장합니다. 프롬프트가 나타나면 토큰을 입력하여 로그인하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## UCF101 데이터셋 불러오기 [[load-ufc101-dataset]]
+
+[UCF-101](https://www.crcv.ucf.edu/data/UCF101.php) 데이터 세트의 하위 집합(subset)을 불러오는 것으로 시작할 수 있습니다. 전체 데이터 세트를 학습하는데 더 많은 시간을 할애하기 전에 데이터의 하위 집합을 불러와 모든 것이 잘 작동하는지 실험하고 확인할 수 있습니다.
+
+```py
+>>> from huggingface_hub import hf_hub_download
+
+>>> hf_dataset_identifier = "sayakpaul/ucf101-subset"
+>>> filename = "UCF101_subset.tar.gz"
+>>> file_path = hf_hub_download(repo_id=hf_dataset_identifier, filename=filename, repo_type="dataset")
+```
+
+데이터 세트의 하위 집합이 다운로드 되면, 압축된 파일의 압축을 해제해야 합니다:
+```py
+>>> import tarfile
+
+>>> with tarfile.open(file_path) as t:
+... t.extractall(".")
+```
+
+전체 데이터 세트는 다음과 같이 구성되어 있습니다.
+
+```bash
+UCF101_subset/
+ train/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+ val/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+ test/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+```
+
+
+정렬된 영상의 경로는 다음과 같습니다:
+
+```bash
+...
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g07_c04.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g07_c06.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g08_c01.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g09_c02.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g09_c06.avi'
+...
+```
+
+동일한 그룹/장면에 속하는 영상 클립은 파일 경로에서 `g`로 표시되어 있습니다. 예를 들면, `v_ApplyEyeMakeup_g07_c04.avi`와 `v_ApplyEyeMakeup_g07_c06.avi` 이 있습니다. 이 둘은 같은 그룹입니다.
+
+검증 및 평가 데이터 분할을 할 때, [데이터 누출(data leakage)](https://www.kaggle.com/code/alexisbcook/data-leakage)을 방지하기 위해 동일한 그룹 / 장면의 영상 클립을 사용하지 않아야 합니다. 이 튜토리얼에서 사용하는 하위 집합은 이러한 정보를 고려하고 있습니다.
+
+그 다음으로, 데이터 세트에 존재하는 라벨을 추출합니다. 또한, 모델을 초기화할 때 도움이 될 딕셔너리(dictionary data type)를 생성합니다.
+
+* `label2id`: 클래스 이름을 정수에 매핑합니다.
+* `id2label`: 정수를 클래스 이름에 매핑합니다.
+
+```py
+>>> class_labels = sorted({str(path).split("/")[2] for path in all_video_file_paths})
+>>> label2id = {label: i for i, label in enumerate(class_labels)}
+>>> id2label = {i: label for label, i in label2id.items()}
+
+>>> print(f"Unique classes: {list(label2id.keys())}.")
+
+# Unique classes: ['ApplyEyeMakeup', 'ApplyLipstick', 'Archery', 'BabyCrawling', 'BalanceBeam', 'BandMarching', 'BaseballPitch', 'Basketball', 'BasketballDunk', 'BenchPress'].
+```
+
+이 데이터 세트에는 총 10개의 고유한 클래스가 있습니다. 각 클래스마다 30개의 영상이 훈련 세트에 있습니다
+
+## 미세 조정하기 위해 모델 가져오기 [[load-a-model-to-fine-tune]]
+
+사전 훈련된 체크포인트와 체크포인트에 연관된 이미지 프로세서를 사용하여 영상 분류 모델을 인스턴스화합니다. 모델의 인코더에는 미리 학습된 매개변수가 제공되며, 분류 헤드(데이터를 분류하는 마지막 레이어)는 무작위로 초기화됩니다. 데이터 세트의 전처리 파이프라인을 작성할 때는 이미지 프로세서가 유용합니다.
+
+```py
+>>> from transformers import VideoMAEImageProcessor, VideoMAEForVideoClassification
+
+>>> model_ckpt = "MCG-NJU/videomae-base"
+>>> image_processor = VideoMAEImageProcessor.from_pretrained(model_ckpt)
+>>> model = VideoMAEForVideoClassification.from_pretrained(
+... model_ckpt,
+... label2id=label2id,
+... id2label=id2label,
+... ignore_mismatched_sizes=True, # provide this in case you're planning to fine-tune an already fine-tuned checkpoint
+... )
+```
+
+모델을 가져오는 동안, 다음과 같은 경고를 마주칠 수 있습니다:
+
+```bash
+Some weights of the model checkpoint at MCG-NJU/videomae-base were not used when initializing VideoMAEForVideoClassification: [..., 'decoder.decoder_layers.1.attention.output.dense.bias', 'decoder.decoder_layers.2.attention.attention.key.weight']
+- This IS expected if you are initializing VideoMAEForVideoClassification from the checkpoint of a model trained on another task or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).
+- This IS NOT expected if you are initializing VideoMAEForVideoClassification from the checkpoint of a model that you expect to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model).
+Some weights of VideoMAEForVideoClassification were not initialized from the model checkpoint at MCG-NJU/videomae-base and are newly initialized: ['classifier.bias', 'classifier.weight']
+You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.
+```
+
+
+위 경고는 우리가 일부 가중치(예: `classifier` 층의 가중치와 편향)를 버리고 새로운 `classifier` 층의 가중치와 편향을 무작위로 초기화하고 있다는 것을 알려줍니다. 이 경우에는 미리 학습된 가중치가 없는 새로운 헤드를 추가하고 있으므로, 라이브러리가 모델을 추론에 사용하기 전에 미세 조정하라고 경고를 보내는 것은 당연합니다. 그리고 이제 우리는 이 모델을 미세 조정할 예정입니다.
+
+**참고** 이 [체크포인트](https://huggingface.co/MCG-NJU/videomae-base-finetuned-kinetics)는 도메인이 많이 중첩된 유사한 다운스트림 작업에 대해 미세 조정하여 얻은 체크포인트이므로 이 작업에서 더 나은 성능을 보일 수 있습니다. `MCG-NJU/videomae-base-finetuned-kinetics` 데이터 세트를 미세 조정하여 얻은 [체크포인트](https://huggingface.co/sayakpaul/videomae-base-finetuned-kinetics-finetuned-ucf101-subset)도 있습니다.
+
+## 훈련을 위한 데이터 세트 준비하기[[prepare-the-datasets-for-training]]
+
+영상 전처리를 위해 [PyTorchVideo 라이브러리](https://pytorchvideo.org/)를 활용할 것입니다. 필요한 종속성을 가져오는 것으로 시작하세요.
+
+```py
+>>> import pytorchvideo.data
+
+>>> from pytorchvideo.transforms import (
+... ApplyTransformToKey,
+... Normalize,
+... RandomShortSideScale,
+... RemoveKey,
+... ShortSideScale,
+... UniformTemporalSubsample,
+... )
+
+>>> from torchvision.transforms import (
+... Compose,
+... Lambda,
+... RandomCrop,
+... RandomHorizontalFlip,
+... Resize,
+... )
+```
+
+학습 데이터 세트 변환에는 '균일한 시간 샘플링(uniform temporal subsampling)', '픽셀 정규화(pixel normalization)', '랜덤 잘라내기(random cropping)' 및 '랜덤 수평 뒤집기(random horizontal flipping)'의 조합을 사용합니다. 검증 및 평가 데이터 세트 변환에는 '랜덤 잘라내기'와 '랜덤 뒤집기'를 제외한 동일한 변환 체인을 유지합니다. 이러한 변환에 대해 자세히 알아보려면 [PyTorchVideo 공식 문서](https://pytorchvideo.org)를 확인하세요.
+
+사전 훈련된 모델과 관련된 이미지 프로세서를 사용하여 다음 정보를 얻을 수 있습니다:
+
+* 영상 프레임 픽셀을 정규화하는 데 사용되는 이미지 평균과 표준 편차
+* 영상 프레임이 조정될 공간 해상도
+
+
+먼저, 몇 가지 상수를 정의합니다.
+
+```py
+>>> mean = image_processor.image_mean
+>>> std = image_processor.image_std
+>>> if "shortest_edge" in image_processor.size:
+... height = width = image_processor.size["shortest_edge"]
+>>> else:
+... height = image_processor.size["height"]
+... width = image_processor.size["width"]
+>>> resize_to = (height, width)
+
+>>> num_frames_to_sample = model.config.num_frames
+>>> sample_rate = 4
+>>> fps = 30
+>>> clip_duration = num_frames_to_sample * sample_rate / fps
+```
+
+이제 데이터 세트에 특화된 전처리(transform)과 데이터 세트 자체를 정의합니다. 먼저 훈련 데이터 세트로 시작합니다:
+
+```py
+>>> train_transform = Compose(
+... [
+... ApplyTransformToKey(
+... key="video",
+... transform=Compose(
+... [
+... UniformTemporalSubsample(num_frames_to_sample),
+... Lambda(lambda x: x / 255.0),
+... Normalize(mean, std),
+... RandomShortSideScale(min_size=256, max_size=320),
+... RandomCrop(resize_to),
+... RandomHorizontalFlip(p=0.5),
+... ]
+... ),
+... ),
+... ]
+... )
+
+>>> train_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "train"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("random", clip_duration),
+... decode_audio=False,
+... transform=train_transform,
+... )
+```
+
+같은 방식의 작업 흐름을 검증과 평가 세트에도 적용할 수 있습니다.
+
+```py
+>>> val_transform = Compose(
+... [
+... ApplyTransformToKey(
+... key="video",
+... transform=Compose(
+... [
+... UniformTemporalSubsample(num_frames_to_sample),
+... Lambda(lambda x: x / 255.0),
+... Normalize(mean, std),
+... Resize(resize_to),
+... ]
+... ),
+... ),
+... ]
+... )
+
+>>> val_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "val"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("uniform", clip_duration),
+... decode_audio=False,
+... transform=val_transform,
+... )
+
+>>> test_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "test"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("uniform", clip_duration),
+... decode_audio=False,
+... transform=val_transform,
+... )
+```
+
+
+**참고**: 위의 데이터 세트의 파이프라인은 [공식 파이토치 예제](https://pytorchvideo.org/docs/tutorial_classification#dataset)에서 가져온 것입니다. 우리는 UCF-101 데이터셋에 맞게 [`pytorchvideo.data.Ucf101()`](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html#pytorchvideo.data.Ucf101) 함수를 사용하고 있습니다. 내부적으로 이 함수는 [`pytorchvideo.data.labeled_video_dataset.LabeledVideoDataset`](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html#pytorchvideo.data.LabeledVideoDataset) 객체를 반환합니다. `LabeledVideoDataset` 클래스는 PyTorchVideo 데이터셋에서 모든 영상 관련 작업의 기본 클래스입니다. 따라서 PyTorchVideo에서 미리 제공하지 않는 사용자 지정 데이터 세트를 사용하려면, 이 클래스를 적절하게 확장하면 됩니다. 더 자세한 사항이 알고 싶다면 `data` API [문서](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html) 를 참고하세요. 또한 위의 예시와 유사한 구조를 갖는 데이터 세트를 사용하고 있다면, `pytorchvideo.data.Ucf101()` 함수를 사용하는 데 문제가 없을 것입니다.
+
+데이터 세트에 영상의 개수를 알기 위해 `num_videos` 인수에 접근할 수 있습니다.
+
+```py
+>>> print(train_dataset.num_videos, val_dataset.num_videos, test_dataset.num_videos)
+# (300, 30, 75)
+```
+
+## 더 나은 디버깅을 위해 전처리 영상 시각화하기[[visualize-the-preprocessed-video-for-better-debugging]]
+
+```py
+>>> import imageio
+>>> import numpy as np
+>>> from IPython.display import Image
+
+>>> def unnormalize_img(img):
+... """Un-normalizes the image pixels."""
+... img = (img * std) + mean
+... img = (img * 255).astype("uint8")
+... return img.clip(0, 255)
+
+>>> def create_gif(video_tensor, filename="sample.gif"):
+... """Prepares a GIF from a video tensor.
+...
+... The video tensor is expected to have the following shape:
+... (num_frames, num_channels, height, width).
+... """
+... frames = []
+... for video_frame in video_tensor:
+... frame_unnormalized = unnormalize_img(video_frame.permute(1, 2, 0).numpy())
+... frames.append(frame_unnormalized)
+... kargs = {"duration": 0.25}
+... imageio.mimsave(filename, frames, "GIF", **kargs)
+... return filename
+
+>>> def display_gif(video_tensor, gif_name="sample.gif"):
+... """Prepares and displays a GIF from a video tensor."""
+... video_tensor = video_tensor.permute(1, 0, 2, 3)
+... gif_filename = create_gif(video_tensor, gif_name)
+... return Image(filename=gif_filename)
+
+>>> sample_video = next(iter(train_dataset))
+>>> video_tensor = sample_video["video"]
+>>> display_gif(video_tensor)
+```
+
+
+
+
+
+## 모델 훈련하기[[train-the-model]]
+
+🤗 Transformers의 [`Trainer`](https://huggingface.co/docs/transformers/main_classes/trainer)를 사용하여 모델을 훈련시켜보세요. `Trainer`를 인스턴스화하려면 훈련 설정과 평가 지표를 정의해야 합니다. 가장 중요한 것은 [`TrainingArguments`](https://huggingface.co/transformers/main_classes/trainer.html#transformers.TrainingArguments)입니다. 이 클래스는 훈련을 구성하는 모든 속성을 포함하며, 훈련 중 체크포인트를 저장할 출력 폴더 이름을 필요로 합니다. 또한 🤗 Hub의 모델 저장소의 모든 정보를 동기화하는 데 도움이 됩니다.
+
+대부분의 훈련 인수는 따로 설명할 필요는 없습니다. 하지만 여기에서 중요한 인수는 `remove_unused_columns=False` 입니다. 이 인자는 모델의 호출 함수에서 사용되지 않는 모든 속성 열(columns)을 삭제합니다. 기본값은 일반적으로 True입니다. 이는 사용되지 않는 기능 열을 삭제하는 것이 이상적이며, 입력을 모델의 호출 함수로 풀기(unpack)가 쉬워지기 때문입니다. 하지만 이 경우에는 `pixel_values`(모델의 입력으로 필수적인 키)를 생성하기 위해 사용되지 않는 기능('video'가 특히 그렇습니다)이 필요합니다. 따라서 remove_unused_columns을 False로 설정해야 합니다.
+
+```py
+>>> from transformers import TrainingArguments, Trainer
+
+>>> model_name = model_ckpt.split("/")[-1]
+>>> new_model_name = f"{model_name}-finetuned-ucf101-subset"
+>>> num_epochs = 4
+
+>>> args = TrainingArguments(
+... new_model_name,
+... remove_unused_columns=False,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... learning_rate=5e-5,
+... per_device_train_batch_size=batch_size,
+... per_device_eval_batch_size=batch_size,
+... warmup_ratio=0.1,
+... logging_steps=10,
+... load_best_model_at_end=True,
+... metric_for_best_model="accuracy",
+... push_to_hub=True,
+... max_steps=(train_dataset.num_videos // batch_size) * num_epochs,
+... )
+```
+
+`pytorchvideo.data.Ucf101()` 함수로 반환되는 데이터 세트는 `__len__` 메소드가 이식되어 있지 않습니다. 따라서, `TrainingArguments`를 인스턴스화할 때 `max_steps`를 정의해야 합니다.
+
+다음으로, 평가지표를 불러오고, 예측값에서 평가지표를 계산할 함수를 정의합니다. 필요한 전처리 작업은 예측된 로짓(logits)에 argmax 값을 취하는 것뿐입니다:
+
+```py
+import evaluate
+
+metric = evaluate.load("accuracy")
+
+
+def compute_metrics(eval_pred):
+ predictions = np.argmax(eval_pred.predictions, axis=1)
+ return metric.compute(predictions=predictions, references=eval_pred.label_ids)
+```
+
+**평가에 대한 참고사항**:
+
+[VideoMAE 논문](https://arxiv.org/abs/2203.12602)에서 저자는 다음과 같은 평가 전략을 사용합니다. 테스트 영상에서 여러 클립을 선택하고 그 클립에 다양한 크롭을 적용하여 집계 점수를 보고합니다. 그러나 이번 튜토리얼에서는 간단함과 간결함을 위해 해당 전략을 고려하지 않습니다.
+
+또한, 예제를 묶어서 배치를 형성하는 `collate_fn`을 정의해야합니다. 각 배치는 `pixel_values`와 `labels`라는 2개의 키로 구성됩니다.
+
+```py
+>>> def collate_fn(examples):
+... # permute to (num_frames, num_channels, height, width)
+... pixel_values = torch.stack(
+... [example["video"].permute(1, 0, 2, 3) for example in examples]
+... )
+... labels = torch.tensor([example["label"] for example in examples])
+... return {"pixel_values": pixel_values, "labels": labels}
+```
+
+그런 다음 이 모든 것을 데이터 세트와 함께 `Trainer`에 전달하기만 하면 됩니다:
+
+```py
+>>> trainer = Trainer(
+... model,
+... args,
+... train_dataset=train_dataset,
+... eval_dataset=val_dataset,
+... processing_class=image_processor,
+... compute_metrics=compute_metrics,
+... data_collator=collate_fn,
+... )
+```
+
+데이터를 이미 처리했는데도 불구하고 `image_processor`를 토크나이저 인수로 넣은 이유는 JSON으로 저장되는 이미지 프로세서 구성 파일이 Hub의 저장소에 업로드되도록 하기 위함입니다.
+
+`train` 메소드를 호출하여 모델을 미세 조정하세요:
+
+```py
+>>> train_results = trainer.train()
+```
+
+학습이 완료되면, 모델을 [`~transformers.Trainer.push_to_hub`] 메소드를 사용하여 허브에 공유하여 누구나 모델을 사용할 수 있도록 합니다:
+```py
+>>> trainer.push_to_hub()
+```
+
+## 추론하기[[inference]]
+
+좋습니다. 이제 미세 조정된 모델을 추론하는 데 사용할 수 있습니다.
+
+추론에 사용할 영상을 불러오세요:
+```py
+>>> sample_test_video = next(iter(test_dataset))
+```
+
+
+
+
+
+미세 조정된 모델을 추론에 사용하는 가장 간단한 방법은 [`pipeline`](https://huggingface.co/docs/transformers/main/en/main_classes/pipelines#transformers.VideoClassificationPipeline)에서 모델을 사용하는 것입니다. 모델로 영상 분류를 하기 위해 `pipeline`을 인스턴스화하고 영상을 전달하세요:
+
+```py
+>>> from transformers import pipeline
+
+>>> video_cls = pipeline(model="my_awesome_video_cls_model")
+>>> video_cls("https://huggingface.co/datasets/sayakpaul/ucf101-subset/resolve/main/v_BasketballDunk_g14_c06.avi")
+[{'score': 0.9272987842559814, 'label': 'BasketballDunk'},
+ {'score': 0.017777055501937866, 'label': 'BabyCrawling'},
+ {'score': 0.01663011871278286, 'label': 'BalanceBeam'},
+ {'score': 0.009560945443809032, 'label': 'BandMarching'},
+ {'score': 0.0068979403004050255, 'label': 'BaseballPitch'}]
+```
+
+만약 원한다면 수동으로 `pipeline`의 결과를 재현할 수 있습니다:
+
+
+```py
+>>> def run_inference(model, video):
+... # (num_frames, num_channels, height, width)
+... perumuted_sample_test_video = video.permute(1, 0, 2, 3)
+... inputs = {
+... "pixel_values": perumuted_sample_test_video.unsqueeze(0),
+... "labels": torch.tensor(
+... [sample_test_video["label"]]
+... ), # this can be skipped if you don't have labels available.
+... }
+
+... device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
+... inputs = {k: v.to(device) for k, v in inputs.items()}
+... model = model.to(device)
+
+... # forward pass
+... with torch.no_grad():
+... outputs = model(**inputs)
+... logits = outputs.logits
+
+... return logits
+```
+
+모델에 입력값을 넣고 `logits`을 반환받으세요:
+
+```py
+>>> logits = run_inference(trained_model, sample_test_video["video"])
+```
+
+`logits`을 디코딩하면, 우리는 다음 결과를 얻을 수 있습니다:
+
+```py
+>>> predicted_class_idx = logits.argmax(-1).item()
+>>> print("Predicted class:", model.config.id2label[predicted_class_idx])
+# Predicted class: BasketballDunk
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/visual_question_answering.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/visual_question_answering.md
new file mode 100644
index 0000000000000000000000000000000000000000..9bc87c071e62b124ed6c941d83242c845fb9aeab
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/visual_question_answering.md
@@ -0,0 +1,375 @@
+
+
+# 시각적 질의응답 (Visual Question Answering)
+
+[[open-in-colab]]
+
+시각적 질의응답(VQA)은 이미지를 기반으로 개방형 질문에 대응하는 작업입니다. 이 작업을 지원하는 모델의 입력은 대부분 이미지와 질문의 조합이며, 출력은 자연어로 된 답변입니다.
+
+VQA의 주요 사용 사례는 다음과 같습니다:
+* 시각 장애인을 위한 접근성 애플리케이션을 구축할 수 있습니다.
+* 교육: 강의나 교과서에 나온 시각 자료에 대한 질문에 답할 수 있습니다. 또한 체험형 전시와 유적 등에서도 VQA를 활용할 수 있습니다.
+* 고객 서비스 및 전자상거래: VQA는 사용자가 제품에 대해 질문할 수 있게 함으로써 사용자 경험을 향상시킬 수 있습니다.
+* 이미지 검색: VQA 모델을 사용하여 원하는 특성을 가진 이미지를 검색할 수 있습니다. 예를 들어 사용자는 "강아지가 있어?"라고 물어봐서 주어진 이미지 묶음에서 강아지가 있는 모든 이미지를 받아볼 수 있습니다.
+
+이 가이드에서 학습할 내용은 다음과 같습니다:
+
+- VQA 모델 중 하나인 [ViLT](../../en/model_doc/vilt)를 [`Graphcore/vqa` 데이터셋](https://huggingface.co/datasets/Graphcore/vqa) 에서 미세조정하는 방법
+- 미세조정된 ViLT 모델로 추론하는 방법
+- BLIP-2 같은 생성 모델로 제로샷 VQA 추론을 실행하는 방법
+
+## ViLT 미세 조정 [[finetuning-vilt]]
+
+ViLT는 Vision Transformer (ViT) 내에 텍스트 임베딩을 포함하여 비전/자연어 사전훈련(VLP; Vision-and-Language Pretraining)을 위한 기본 디자인을 제공합니다.
+ViLT 모델은 비전 트랜스포머(ViT)에 텍스트 임베딩을 넣어 비전/언어 사전훈련(VLP; Vision-and-Language Pre-training)을 위한 기본적인 디자인을 갖췄습니다. 이 모델은 여러 다운스트림 작업에 사용할 수 있습니다. VQA 태스크에서는 (`[CLS]` 토큰의 최종 은닉 상태 위에 선형 레이어인) 분류 헤더가 있으며 무작위로 초기화됩니다.
+따라서 여기에서 시각적 질의응답은 **분류 문제**로 취급됩니다.
+
+최근의 BLIP, BLIP-2, InstructBLIP와 같은 모델들은 VQA를 생성형 작업으로 간주합니다. 가이드의 후반부에서는 이런 모델들을 사용하여 제로샷 VQA 추론을 하는 방법에 대해 설명하겠습니다.
+
+시작하기 전 필요한 모든 라이브러리를 설치했는지 확인하세요.
+
+```bash
+pip install -q transformers datasets
+```
+
+커뮤니티에 모델을 공유하는 것을 권장 드립니다. Hugging Face 계정에 로그인하여 🤗 Hub에 업로드할 수 있습니다.
+메시지가 나타나면 로그인할 토큰을 입력하세요:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+모델 체크포인트를 전역 변수로 선언하세요.
+
+```py
+>>> model_checkpoint = "dandelin/vilt-b32-mlm"
+```
+
+## 데이터 가져오기 [[load-the-data]]
+
+이 가이드에서는 `Graphcore/vqa` 데이터세트의 작은 샘플을 사용합니다. 전체 데이터세트는 [🤗 Hub](https://huggingface.co/datasets/Graphcore/vqa) 에서 확인할 수 있습니다.
+
+[`Graphcore/vqa` 데이터세트](https://huggingface.co/datasets/Graphcore/vqa) 의 대안으로 공식 [VQA 데이터세트 페이지](https://visualqa.org/download.html) 에서 동일한 데이터를 수동으로 다운로드할 수 있습니다. 직접 공수한 데이터로 튜토리얼을 따르고 싶다면 [이미지 데이터세트 만들기](https://huggingface.co/docs/datasets/image_dataset#loading-script) 라는
+🤗 Datasets 문서를 참조하세요.
+
+검증 데이터의 첫 200개 항목을 불러와 데이터세트의 특성을 확인해 보겠습니다:
+
+```python
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("Graphcore/vqa", split="validation[:200]")
+>>> dataset
+Dataset({
+ features: ['question', 'question_type', 'question_id', 'image_id', 'answer_type', 'label'],
+ num_rows: 200
+})
+```
+
+예제를 하나 뽑아 데이터세트의 특성을 이해해 보겠습니다.
+
+```py
+>>> dataset[0]
+{'question': 'Where is he looking?',
+ 'question_type': 'none of the above',
+ 'question_id': 262148000,
+ 'image_id': '/root/.cache/huggingface/datasets/downloads/extracted/ca733e0e000fb2d7a09fbcc94dbfe7b5a30750681d0e965f8e0a23b1c2f98c75/val2014/COCO_val2014_000000262148.jpg',
+ 'answer_type': 'other',
+ 'label': {'ids': ['at table', 'down', 'skateboard', 'table'],
+ 'weights': [0.30000001192092896,
+ 1.0,
+ 0.30000001192092896,
+ 0.30000001192092896]}}
+```
+
+데이터세트에는 다음과 같은 특성이 포함되어 있습니다:
+* `question`: 이미지에 대한 질문
+* `image_id`: 질문과 관련된 이미지의 경로
+* `label`: 데이터의 레이블 (annotations)
+
+나머지 특성들은 필요하지 않기 때문에 삭제해도 됩니다:
+
+```py
+>>> dataset = dataset.remove_columns(['question_type', 'question_id', 'answer_type'])
+```
+
+보시다시피 `label` 특성은 같은 질문마다 답변이 여러 개 있을 수 있습니다. 모두 다른 데이터 라벨러들로부터 수집되었기 때문인데요. 질문의 답변은 주관적일 수 있습니다. 이 경우 질문은 "그는 어디를 보고 있나요?" 였지만, 어떤 사람들은 "아래"로 레이블을 달았고, 다른 사람들은 "테이블" 또는 "스케이트보드" 등으로 주석을 달았습니다.
+
+아래의 이미지를 보고 어떤 답변을 선택할 것인지 생각해 보세요:
+
+```python
+>>> from PIL import Image
+
+>>> image = Image.open(dataset[0]['image_id'])
+>>> image
+```
+
+
+
+
+
+질문과 답변의 모호성으로 인해 이러한 데이터세트는 여러 개의 답변이 가능하므로 다중 레이블 분류 문제로 처리됩니다. 게다가, 원핫(one-hot) 인코딩 벡터를 생성하기보다는 레이블에서 특정 답변이 나타나는 횟수를 기반으로 소프트 인코딩을 생성합니다.
+
+위의 예시에서 "아래"라는 답변이 다른 답변보다 훨씬 더 자주 선택되었기 때문에 데이터세트에서 `weight`라고 불리는 점수로 1.0을 가지며, 나머지 답변들은 1.0 미만의 점수를 가집니다.
+
+적절한 분류 헤더로 모델을 나중에 인스턴스화하기 위해 레이블을 정수로 매핑한 딕셔너리 하나, 반대로 정수를 레이블로 매핑한 딕셔너리 하나 총 2개의 딕셔너리를 생성하세요:
+
+```py
+>>> import itertools
+
+>>> labels = [item['ids'] for item in dataset['label']]
+>>> flattened_labels = list(itertools.chain(*labels))
+>>> unique_labels = list(set(flattened_labels))
+
+>>> label2id = {label: idx for idx, label in enumerate(unique_labels)}
+>>> id2label = {idx: label for label, idx in label2id.items()}
+```
+
+이제 매핑이 완료되었으므로 문자열 답변을 해당 id로 교체하고, 데이터세트의 더 편리한 후처리를 위해 편평화 할 수 있습니다.
+
+```python
+>>> def replace_ids(inputs):
+... inputs["label"]["ids"] = [label2id[x] for x in inputs["label"]["ids"]]
+... return inputs
+
+
+>>> dataset = dataset.map(replace_ids)
+>>> flat_dataset = dataset.flatten()
+>>> flat_dataset.features
+{'question': Value(dtype='string', id=None),
+ 'image_id': Value(dtype='string', id=None),
+ 'label.ids': Sequence(feature=Value(dtype='int64', id=None), length=-1, id=None),
+ 'label.weights': Sequence(feature=Value(dtype='float64', id=None), length=-1, id=None)}
+```
+
+## 데이터 전처리 [[preprocessing-data]]
+
+다음 단계는 모델을 위해 이미지와 텍스트 데이터를 준비하기 위해 ViLT 프로세서를 가져오는 것입니다.
+[`ViltProcessor`]는 BERT 토크나이저와 ViLT 이미지 프로세서를 편리하게 하나의 프로세서로 묶습니다:
+
+```py
+>>> from transformers import ViltProcessor
+
+>>> processor = ViltProcessor.from_pretrained(model_checkpoint)
+```
+
+데이터를 전처리하려면 이미지와 질문을 [`ViltProcessor`]로 인코딩해야 합니다. 프로세서는 [`BertTokenizerFast`]로 텍스트를 토크나이즈하고 텍스트 데이터를 위해 `input_ids`, `attention_mask` 및 `token_type_ids`를 생성합니다.
+이미지는 [`ViltImageProcessor`]로 이미지를 크기 조정하고 정규화하며, `pixel_values`와 `pixel_mask`를 생성합니다.
+
+이런 전처리 단계는 모두 내부에서 이루어지므로, `processor`를 호출하기만 하면 됩니다. 하지만 아직 타겟 레이블이 완성되지 않았습니다. 타겟의 표현에서 각 요소는 가능한 답변(레이블)에 해당합니다. 정확한 답변의 요소는 해당 점수(weight)를 유지시키고 나머지 요소는 0으로 설정해야 합니다.
+
+아래 함수가 위에서 설명한대로 이미지와 질문에 `processor`를 적용하고 레이블을 형식에 맞춥니다:
+
+```py
+>>> import torch
+
+>>> def preprocess_data(examples):
+... image_paths = examples['image_id']
+... images = [Image.open(image_path) for image_path in image_paths]
+... texts = examples['question']
+
+... encoding = processor(images, texts, padding="max_length", truncation=True, return_tensors="pt")
+
+... for k, v in encoding.items():
+... encoding[k] = v.squeeze()
+
+... targets = []
+
+... for labels, scores in zip(examples['label.ids'], examples['label.weights']):
+... target = torch.zeros(len(id2label))
+
+... for label, score in zip(labels, scores):
+... target[label] = score
+
+... targets.append(target)
+
+... encoding["labels"] = targets
+
+... return encoding
+```
+
+전체 데이터세트에 전처리 함수를 적용하려면 🤗 Datasets의 [`~datasets.map`] 함수를 사용하십시오. `batched=True`를 설정하여 데이터세트의 여러 요소를 한 번에 처리함으로써 `map`을 더 빠르게 할 수 있습니다. 이 시점에서 필요하지 않은 열은 제거하세요.
+
+```py
+>>> processed_dataset = flat_dataset.map(preprocess_data, batched=True, remove_columns=['question','question_type', 'question_id', 'image_id', 'answer_type', 'label.ids', 'label.weights'])
+>>> processed_dataset
+Dataset({
+ features: ['input_ids', 'token_type_ids', 'attention_mask', 'pixel_values', 'pixel_mask', 'labels'],
+ num_rows: 200
+})
+```
+
+마지막 단계로, [`DefaultDataCollator`]를 사용하여 예제로 쓸 배치를 생성하세요:
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+## 모델 훈련 [[train-the-model]]
+
+이제 모델을 훈련하기 위해 준비되었습니다! [`ViltForQuestionAnswering`]으로 ViLT를 가져올 차례입니다. 레이블의 수와 레이블 매핑을 지정하세요:
+
+```py
+>>> from transformers import ViltForQuestionAnswering
+
+>>> model = ViltForQuestionAnswering.from_pretrained(model_checkpoint, num_labels=len(id2label), id2label=id2label, label2id=label2id)
+```
+
+이 시점에서는 다음 세 단계만 남았습니다:
+
+1. [`TrainingArguments`]에서 훈련 하이퍼파라미터를 정의하세요:
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> repo_id = "MariaK/vilt_finetuned_200"
+
+>>> training_args = TrainingArguments(
+... output_dir=repo_id,
+... per_device_train_batch_size=4,
+... num_train_epochs=20,
+... save_steps=200,
+... logging_steps=50,
+... learning_rate=5e-5,
+... save_total_limit=2,
+... remove_unused_columns=False,
+... push_to_hub=True,
+... )
+```
+
+2. 모델, 데이터세트, 프로세서, 데이터 콜레이터와 함께 훈련 인수를 [`Trainer`]에 전달하세요:
+
+```py
+>>> from transformers import Trainer
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... data_collator=data_collator,
+... train_dataset=processed_dataset,
+... processing_class=processor,
+... )
+```
+
+3. [`~Trainer.train`]을 호출하여 모델을 미세 조정하세요:
+
+```py
+>>> trainer.train()
+```
+
+훈련이 완료되면, [`~Trainer.push_to_hub`] 메소드를 사용하여 🤗 Hub에 모델을 공유하세요:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+## 추론 [[inference]]
+
+ViLT 모델을 미세 조정하고 🤗 Hub에 업로드했다면 추론에 사용할 수 있습니다. 미세 조정된 모델을 추론에 사용해보는 가장 간단한 방법은 [`Pipeline`]에서 사용하는 것입니다.
+
+```py
+>>> from transformers import pipeline
+
+>>> pipe = pipeline("visual-question-answering", model="MariaK/vilt_finetuned_200")
+```
+
+이 가이드의 모델은 200개의 예제에서만 훈련되었으므로 그다지 많은 것을 기대할 수는 없습니다. 데이터세트의 첫 번째 예제를 사용하여 추론 결과를 설명해보겠습니다:
+
+```py
+>>> example = dataset[0]
+>>> image = Image.open(example['image_id'])
+>>> question = example['question']
+>>> print(question)
+>>> pipe(image, question, top_k=1)
+"Where is he looking?"
+[{'score': 0.5498199462890625, 'answer': 'down'}]
+```
+
+비록 확신은 별로 없지만, 모델은 실제로 무언가를 배웠습니다. 더 많은 예제와 더 긴 훈련 기간이 주어진다면 분명 더 나은 결과를 얻을 수 있을 것입니다!
+
+원한다면 파이프라인의 결과를 수동으로 복제할 수도 있습니다:
+1. 이미지와 질문을 가져와서 프로세서를 사용하여 모델에 준비합니다.
+2. 전처리된 결과를 모델에 전달합니다.
+3. 로짓에서 가장 가능성 있는 답변의 id를 가져와서 `id2label`에서 실제 답변을 찾습니다.
+
+```py
+>>> processor = ViltProcessor.from_pretrained("MariaK/vilt_finetuned_200")
+
+>>> image = Image.open(example['image_id'])
+>>> question = example['question']
+
+>>> # prepare inputs
+>>> inputs = processor(image, question, return_tensors="pt")
+
+>>> model = ViltForQuestionAnswering.from_pretrained("MariaK/vilt_finetuned_200")
+
+>>> # forward pass
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> logits = outputs.logits
+>>> idx = logits.argmax(-1).item()
+>>> print("Predicted answer:", model.config.id2label[idx])
+Predicted answer: down
+```
+
+## 제로샷 VQA [[zeroshot-vqa]]
+
+이전 모델은 VQA를 분류 문제로 처리했습니다. BLIP, BLIP-2 및 InstructBLIP와 같은 최근의 모델은 VQA를 생성 작업으로 접근합니다. [BLIP-2](../../en/model_doc/blip-2)를 예로 들어 보겠습니다. 이 모델은 사전훈련된 비전 인코더와 LLM의 모든 조합을 사용할 수 있는 새로운 비전-자연어 사전 학습 패러다임을 도입했습니다. ([BLIP-2 블로그 포스트](https://huggingface.co/blog/blip-2)를 통해 더 자세히 알아볼 수 있어요)
+이를 통해 시각적 질의응답을 포함한 여러 비전-자연어 작업에서 SOTA를 달성할 수 있었습니다.
+
+이 모델을 어떻게 VQA에 사용할 수 있는지 설명해 보겠습니다. 먼저 모델을 가져와 보겠습니다. 여기서 GPU가 사용 가능한 경우 모델을 명시적으로 GPU로 전송할 것입니다. 이전에는 훈련할 때 쓰지 않은 이유는 [`Trainer`]가 이 부분을 자동으로 처리하기 때문입니다:
+
+```py
+>>> from transformers import AutoProcessor, Blip2ForConditionalGeneration
+>>> import torch
+
+>>> processor = AutoProcessor.from_pretrained("Salesforce/blip2-opt-2.7b")
+>>> model = Blip2ForConditionalGeneration.from_pretrained("Salesforce/blip2-opt-2.7b", torch_dtype=torch.float16)
+>>> device = "cuda" if torch.cuda.is_available() else "cpu"
+>>> model.to(device)
+```
+
+모델은 이미지와 텍스트를 입력으로 받으므로, VQA 데이터세트의 첫 번째 예제에서와 동일한 이미지/질문 쌍을 사용해 보겠습니다:
+
+```py
+>>> example = dataset[0]
+>>> image = Image.open(example['image_id'])
+>>> question = example['question']
+```
+
+BLIP-2를 시각적 질의응답 작업에 사용하려면 텍스트 프롬프트가 `Question: {} Answer:` 형식을 따라야 합니다.
+
+```py
+>>> prompt = f"Question: {question} Answer:"
+```
+
+이제 모델의 프로세서로 이미지/프롬프트를 전처리하고, 처리된 입력을 모델을 통해 전달하고, 출력을 디코드해야 합니다:
+
+```py
+>>> inputs = processor(image, text=prompt, return_tensors="pt").to(device, torch.float16)
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0].strip()
+>>> print(generated_text)
+"He is looking at the crowd"
+```
+
+보시다시피 모델은 군중을 인식하고, 얼굴의 방향(아래쪽을 보고 있음)을 인식했지만, 군중이 스케이터 뒤에 있다는 사실을 놓쳤습니다. 그러나 사람이 직접 라벨링한 데이터셋을 얻을 수 없는 경우에, 이 접근법은 빠르게 유용한 결과를 생성할 수 있습니다.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/zero_shot_image_classification.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/zero_shot_image_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..f824de93b8652201f72e9b78aa8b2ff634047cb8
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/zero_shot_image_classification.md
@@ -0,0 +1,144 @@
+
+
+# 제로샷(zero-shot) 이미지 분류[[zeroshot-image-classification]]
+
+[[open-in-colab]]
+
+제로샷(zero-shot) 이미지 분류는 특정 카테고리의 예시가 포함된 데이터를 학습되지 않은 모델을 사용해 이미지 분류를 수행하는 작업입니다.
+
+일반적으로 이미지 분류를 위해서는 레이블이 달린 특정 이미지 데이터로 모델 학습이 필요하며, 이 모델은 특정 이미지의 특징을 레이블에 "매핑"하는 방법을 학습합니다.
+새로운 레이블이 있는 분류 작업에 이러한 모델을 사용해야 하는 경우에는, 모델을 "재보정"하기 위해 미세 조정이 필요합니다.
+
+이와 대조적으로, 제로샷 또는 개방형 어휘(open vocabulary) 이미지 분류 모델은 일반적으로 대규모 이미지 데이터와 해당 설명에 대해 학습된 멀티모달(multimodal) 모델입니다.
+이러한 모델은 제로샷 이미지 분류를 포함한 많은 다운스트림 작업에 사용할 수 있는 정렬된(aligned) 비전 언어 표현을 학습합니다.
+
+이는 이미지 분류에 대한 보다 유연한 접근 방식으로, 추가 학습 데이터 없이 새로운 레이블이나 학습하지 못한 카테고리에 대해 모델을 일반화할 수 있습니다.
+또한, 사용자가 대상 개체에 대한 자유 형식의 텍스트 설명으로 이미지를 검색할 수 있습니다.
+
+이번 가이드에서 배울 내용은 다음과 같습니다:
+
+* 제로샷 이미지 분류 파이프라인 만들기
+* 직접 제로샷 이미지 분류 모델 추론 실행하기
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+
+```bash
+pip install -q transformers
+```
+
+## 제로샷(zero-shot) 이미지 분류 파이프라인[[zeroshot-image-classification-pipeline]]
+
+[`pipeline`]을 활용하면 가장 간단하게 제로샷 이미지 분류를 지원하는 모델로 추론해볼 수 있습니다.
+[Hugging Face Hub에 업로드된 체크포인트](https://huggingface.co/models?pipeline_tag=zero-shot-image-classification&sort=downloads)에서 파이프라인을 인스턴스화합니다.
+
+```python
+>>> from transformers import pipeline
+
+>>> checkpoint = "openai/clip-vit-large-patch14"
+>>> detector = pipeline(model=checkpoint, task="zero-shot-image-classification")
+```
+
+다음으로, 분류하고 싶은 이미지를 선택하세요.
+
+```py
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "https://unsplash.com/photos/g8oS8-82DxI/download?ixid=MnwxMjA3fDB8MXx0b3BpY3x8SnBnNktpZGwtSGt8fHx8fDJ8fDE2NzgxMDYwODc&force=true&w=640"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> image
+```
+
+
+
+
+
+이미지와 해당 이미지의 후보 레이블인 `candidate_labels`를 파이프라인으로 전달합니다.
+여기서는 이미지를 직접 전달하지만, 컴퓨터에 저장된 이미지의 경로나 url로 전달할 수도 있습니다.
+`candidate_labels`는 이 예시처럼 간단한 단어일 수도 있고 좀 더 설명적인 단어일 수도 있습니다.
+
+```py
+>>> predictions = classifier(image, candidate_labels=["fox", "bear", "seagull", "owl"])
+>>> predictions
+[{'score': 0.9996670484542847, 'label': 'owl'},
+ {'score': 0.000199399160919711, 'label': 'seagull'},
+ {'score': 7.392891711788252e-05, 'label': 'fox'},
+ {'score': 5.96074532950297e-05, 'label': 'bear'}]
+```
+
+## 직접 제로샷(zero-shot) 이미지 분류하기[[zeroshot-image-classification-by-hand]]
+
+이제 제로샷 이미지 분류 파이프라인 사용 방법을 살펴보았으니, 실행하는 방법을 살펴보겠습니다.
+
+[Hugging Face Hub에 업로드된 체크포인트](https://huggingface.co/models?pipeline_tag=zero-shot-image-classification&sort=downloads)에서 모델과 프로세서를 가져오는 것으로 시작합니다.
+여기서는 이전과 동일한 체크포인트를 사용하겠습니다:
+
+```py
+>>> from transformers import AutoProcessor, AutoModelForZeroShotImageClassification
+
+>>> model = AutoModelForZeroShotImageClassification.from_pretrained(checkpoint)
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+```
+
+다른 이미지를 사용해 보겠습니다.
+
+```py
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "https://unsplash.com/photos/xBRQfR2bqNI/download?ixid=MnwxMjA3fDB8MXxhbGx8fHx8fHx8fHwxNjc4Mzg4ODEx&force=true&w=640"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> image
+```
+
+
+
+
+
+프로세서를 사용해 모델의 입력을 준비합니다.
+프로세서는 모델의 입력으로 사용하기 위해 이미지 크기를 변환하고 정규화하는 이미지 프로세서와 텍스트 입력을 처리하는 토크나이저로 구성됩니다.
+
+```py
+>>> candidate_labels = ["tree", "car", "bike", "cat"]
+>>> inputs = processor(images=image, text=candidate_labels, return_tensors="pt", padding=True)
+```
+
+모델에 입력을 전달하고, 결과를 후처리합니다:
+
+```py
+>>> import torch
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> logits = outputs.logits_per_image[0]
+>>> probs = logits.softmax(dim=-1).numpy()
+>>> scores = probs.tolist()
+
+>>> result = [
+... {"score": score, "label": candidate_label}
+... for score, candidate_label in sorted(zip(probs, candidate_labels), key=lambda x: -x[0])
+... ]
+
+>>> result
+[{'score': 0.998572, 'label': 'car'},
+ {'score': 0.0010570387, 'label': 'bike'},
+ {'score': 0.0003393686, 'label': 'tree'},
+ {'score': 3.1572064e-05, 'label': 'cat'}]
+```
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/zero_shot_object_detection.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/zero_shot_object_detection.md
new file mode 100644
index 0000000000000000000000000000000000000000..8e9b52e8c7a20fd5e14b5c3288dcbf2e758f6294
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks/zero_shot_object_detection.md
@@ -0,0 +1,307 @@
+
+
+# 제로샷(zero-shot) 객체 탐지[[zeroshot-object-detection]]
+
+[[open-in-colab]]
+
+일반적으로 [객체 탐지](object_detection)에 사용되는 모델을 학습하기 위해서는 레이블이 지정된 이미지 데이터 세트가 필요합니다.
+그리고 학습 데이터에 존재하는 클래스(레이블)만 탐지할 수 있다는 한계점이 있습니다.
+
+다른 방식을 사용하는 [OWL-ViT](../model_doc/owlvit) 모델로 제로샷 객체 탐지가 가능합니다.
+OWL-ViT는 개방형 어휘(open-vocabulary) 객체 탐지기입니다.
+즉, 레이블이 지정된 데이터 세트에 미세 조정하지 않고 자유 텍스트 쿼리를 기반으로 이미지에서 객체를 탐지할 수 있습니다.
+
+OWL-ViT 모델은 멀티 모달 표현을 활용해 개방형 어휘 탐지(open-vocabulary detection)를 수행합니다.
+[CLIP](../model_doc/clip) 모델에 경량화(lightweight)된 객체 분류와 지역화(localization) 헤드를 결합합니다.
+개방형 어휘 탐지는 CLIP의 텍스트 인코더로 free-text 쿼리를 임베딩하고, 객체 분류와 지역화 헤드의 입력으로 사용합니다.
+이미지와 해당 텍스트 설명을 연결하면 ViT가 이미지 패치(image patches)를 입력으로 처리합니다.
+OWL-ViT 모델의 저자들은 CLIP 모델을 처음부터 학습(scratch learning)한 후에, bipartite matching loss를 사용하여 표준 객체 인식 데이터셋으로 OWL-ViT 모델을 미세 조정했습니다.
+
+이 접근 방식을 사용하면 모델은 레이블이 지정된 데이터 세트에 대한 사전 학습 없이도 텍스트 설명을 기반으로 객체를 탐지할 수 있습니다.
+
+이번 가이드에서는 OWL-ViT 모델의 사용법을 다룰 것입니다:
+- 텍스트 프롬프트 기반 객체 탐지
+- 일괄 객체 탐지
+- 이미지 가이드 객체 탐지
+
+시작하기 전에 필요한 라이브러리가 모두 설치되어 있는지 확인하세요:
+```bash
+pip install -q transformers
+```
+
+## 제로샷(zero-shot) 객체 탐지 파이프라인[[zeroshot-object-detection-pipeline]]
+
+[`pipeline`]을 활용하면 가장 간단하게 OWL-ViT 모델을 추론해볼 수 있습니다.
+[Hugging Face Hub에 업로드된 체크포인트](https://huggingface.co/models?pipeline_tag=zero-shot-image-classification&sort=downloads)에서 제로샷(zero-shot) 객체 탐지용 파이프라인을 인스턴스화합니다:
+
+```python
+>>> from transformers import pipeline
+
+>>> checkpoint = "google/owlvit-base-patch32"
+>>> detector = pipeline(model=checkpoint, task="zero-shot-object-detection")
+```
+
+다음으로, 객체를 탐지하고 싶은 이미지를 선택하세요.
+여기서는 [NASA](https://www.nasa.gov/multimedia/imagegallery/index.html) Great Images 데이터 세트의 일부인 우주비행사 에일린 콜린스(Eileen Collins) 사진을 사용하겠습니다.
+
+```py
+>>> import skimage
+>>> import numpy as np
+>>> from PIL import Image
+
+>>> image = skimage.data.astronaut()
+>>> image = Image.fromarray(np.uint8(image)).convert("RGB")
+
+>>> image
+```
+
+
+
+## 텍스트 프롬프트 기반 객체 탐지[[textprompted-zeroshot-object-detection-by-hand]]
+
+제로샷 객체 탐지 파이프라인 사용법에 대해 살펴보았으니, 이제 동일한 결과를 복제해보겠습니다.
+
+[Hugging Face Hub에 업로드된 체크포인트](https://huggingface.co/models?other=owlvit)에서 관련 모델과 프로세서를 가져오는 것으로 시작합니다.
+여기서는 이전과 동일한 체크포인트를 사용하겠습니다:
+
+```py
+>>> from transformers import AutoProcessor, AutoModelForZeroShotObjectDetection
+
+>>> model = AutoModelForZeroShotObjectDetection.from_pretrained(checkpoint)
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+```
+
+다른 이미지를 사용해 보겠습니다:
+
+```py
+>>> import requests
+
+>>> url = "https://unsplash.com/photos/oj0zeY2Ltk4/download?ixid=MnwxMjA3fDB8MXxzZWFyY2h8MTR8fHBpY25pY3xlbnwwfHx8fDE2Nzc0OTE1NDk&force=true&w=640"
+>>> im = Image.open(requests.get(url, stream=True).raw)
+>>> im
+```
+
+
+
+
+
+프로세서를 사용해 모델의 입력을 준비합니다.
+프로세서는 모델의 입력으로 사용하기 위해 이미지 크기를 변환하고 정규화하는 이미지 프로세서와 텍스트 입력을 처리하는 [`CLIPTokenizer`]로 구성됩니다.
+
+```py
+>>> text_queries = ["hat", "book", "sunglasses", "camera"]
+>>> inputs = processor(text=text_queries, images=im, return_tensors="pt")
+```
+
+모델에 입력을 전달하고 결과를 후처리 및 시각화합니다.
+이미지 프로세서가 모델에 이미지를 입력하기 전에 이미지 크기를 조정했기 때문에, [`~OwlViTImageProcessor.post_process_object_detection`] 메소드를 사용해
+예측값의 바운딩 박스(bounding box)가 원본 이미지의 좌표와 상대적으로 동일한지 확인해야 합니다.
+
+```py
+>>> import torch
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+... target_sizes = torch.tensor([im.size[::-1]])
+... results = processor.post_process_object_detection(outputs, threshold=0.1, target_sizes=target_sizes)[0]
+
+>>> draw = ImageDraw.Draw(im)
+
+>>> scores = results["scores"].tolist()
+>>> labels = results["labels"].tolist()
+>>> boxes = results["boxes"].tolist()
+
+>>> for box, score, label in zip(boxes, scores, labels):
+... xmin, ymin, xmax, ymax = box
+... draw.rectangle((xmin, ymin, xmax, ymax), outline="red", width=1)
+... draw.text((xmin, ymin), f"{text_queries[label]}: {round(score,2)}", fill="white")
+
+>>> im
+```
+
+
+
+
+
+## 일괄 처리[[batch-processing]]
+
+여러 이미지와 텍스트 쿼리를 전달하여 여러 이미지에서 서로 다른(또는 동일한) 객체를 검색할 수 있습니다.
+일괄 처리를 위해서 텍스트 쿼리는 이중 리스트로, 이미지는 PIL 이미지, PyTorch 텐서, 또는 NumPy 배열로 이루어진 리스트로 프로세서에 전달해야 합니다.
+
+```py
+>>> images = [image, im]
+>>> text_queries = [
+... ["human face", "rocket", "nasa badge", "star-spangled banner"],
+... ["hat", "book", "sunglasses", "camera"],
+... ]
+>>> inputs = processor(text=text_queries, images=images, return_tensors="pt")
+```
+
+이전에는 후처리를 위해 단일 이미지의 크기를 텐서로 전달했지만, 튜플을 전달할 수 있고, 여러 이미지를 처리하는 경우에는 튜플로 이루어진 리스트를 전달할 수도 있습니다.
+아래 두 예제에 대한 예측을 생성하고, 두 번째 이미지(`image_idx = 1`)를 시각화해 보겠습니다.
+
+```py
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+... target_sizes = [x.size[::-1] for x in images]
+... results = processor.post_process_object_detection(outputs, threshold=0.1, target_sizes=target_sizes)
+
+>>> image_idx = 1
+>>> draw = ImageDraw.Draw(images[image_idx])
+
+>>> scores = results[image_idx]["scores"].tolist()
+>>> labels = results[image_idx]["labels"].tolist()
+>>> boxes = results[image_idx]["boxes"].tolist()
+
+>>> for box, score, label in zip(boxes, scores, labels):
+... xmin, ymin, xmax, ymax = box
+... draw.rectangle((xmin, ymin, xmax, ymax), outline="red", width=1)
+... draw.text((xmin, ymin), f"{text_queries[image_idx][label]}: {round(score,2)}", fill="white")
+
+>>> images[image_idx]
+```
+
+
+
+
+
+## 이미지 가이드 객체 탐지[[imageguided-object-detection]]
+
+텍스트 쿼리를 이용한 제로샷 객체 탐지 외에도 OWL-ViT 모델은 이미지 가이드 객체 탐지 기능을 제공합니다.
+이미지를 쿼리로 사용해 대상 이미지에서 유사한 객체를 찾을 수 있다는 의미입니다.
+텍스트 쿼리와 달리 하나의 예제 이미지에서만 가능합니다.
+
+소파에 고양이 두 마리가 있는 이미지를 대상 이미지(target image)로, 고양이 한 마리가 있는 이미지를 쿼리로 사용해보겠습니다:
+
+```py
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image_target = Image.open(requests.get(url, stream=True).raw)
+
+>>> query_url = "http://images.cocodataset.org/val2017/000000524280.jpg"
+>>> query_image = Image.open(requests.get(query_url, stream=True).raw)
+```
+
+다음 이미지를 살펴보겠습니다:
+
+```py
+>>> import matplotlib.pyplot as plt
+
+>>> fig, ax = plt.subplots(1, 2)
+>>> ax[0].imshow(image_target)
+>>> ax[1].imshow(query_image)
+```
+
+
+
+
+
+전처리 단계에서 텍스트 쿼리 대신에 `query_images`를 사용합니다:
+
+```py
+>>> inputs = processor(images=image_target, query_images=query_image, return_tensors="pt")
+```
+
+예측의 경우, 모델에 입력을 전달하는 대신 [`~OwlViTForObjectDetection.image_guided_detection`]에 전달합니다.
+레이블이 없다는 점을 제외하면 이전과 동일합니다.
+이전과 동일하게 이미지를 시각화합니다.
+
+```py
+>>> with torch.no_grad():
+... outputs = model.image_guided_detection(**inputs)
+... target_sizes = torch.tensor([image_target.size[::-1]])
+... results = processor.post_process_image_guided_detection(outputs=outputs, target_sizes=target_sizes)[0]
+
+>>> draw = ImageDraw.Draw(image_target)
+
+>>> scores = results["scores"].tolist()
+>>> boxes = results["boxes"].tolist()
+
+>>> for box, score, label in zip(boxes, scores, labels):
+... xmin, ymin, xmax, ymax = box
+... draw.rectangle((xmin, ymin, xmax, ymax), outline="white", width=4)
+
+>>> image_target
+```
+
+
+
+
+
+OWL-ViT 모델을 추론하고 싶다면 아래 데모를 확인하세요:
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks_explained.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks_explained.md
new file mode 100644
index 0000000000000000000000000000000000000000..78c90849bb89bfd71a4a9d554e443c8246a1dec6
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tasks_explained.md
@@ -0,0 +1,295 @@
+
+
+# 🤗 Transformers로 작업을 해결하는 방법[[how-transformers-solve-tasks]]
+
+[🤗 Transformers로 할 수 있는 작업](task_summary)에서 자연어 처리(NLP), 음성 및 오디오, 컴퓨터 비전 작업 등의 중요한 응용을 배웠습니다. 이 페이지에서는 모델이 이러한 작업을 어떻게 해결하는지 자세히 살펴보고 내부에서 어떤 일이 일어나는지 설명합니다. 주어진 작업을 해결하는 많은 방법이 있으며, 일부 모델은 특정 기술을 구현하거나 심지어 새로운 방식으로 작업에 접근할 수도 있지만, Transformer 모델의 경우 일반적인 아이디어는 동일합니다. 유연한 아키텍처 덕분에 대부분의 모델은 인코더, 디코더 또는 인코더-디코더 구조의 변형입니다. Transformer 모델뿐만 아니라 우리의 라이브러리에는 오늘날 컴퓨터 비전 작업에 사용되는 몇 가지 합성곱 신경망(CNNs)도 있습니다. 또한, 우리는 현대 CNN의 작동 방식에 대해 설명할 것입니다.
+
+작업이 어떻게 해결되는지 설명하기 위해, 유용한 예측을 출력하고자 모델 내부에서 어떤 일이 일어나는지 살펴봅니다.
+
+- 오디오 분류 및 자동 음성 인식(ASR)을 위한 [Wav2Vec2](model_doc/wav2vec2)
+- 이미지 분류를 위한 [Vision Transformer (ViT)](model_doc/vit) 및 [ConvNeXT](model_doc/convnext)
+- 객체 탐지를 위한 [DETR](model_doc/detr)
+- 이미지 분할을 위한 [Mask2Former](model_doc/mask2former)
+- 깊이 추정을 위한 [GLPN](model_doc/glpn)
+- 인코더를 사용하는 텍스트 분류, 토큰 분류 및 질의응답과 같은 NLP 작업을 위한 [BERT](model_doc/bert)
+- 디코더를 사용하는 텍스트 생성과 같은 NLP 작업을 위한 [GPT2](model_doc/gpt2)
+- 인코더-디코더를 사용하는 요약 및 번역과 같은 NLP 작업을 위한 [BART](model_doc/bart)
+
+
+
+더 나아가기 전에, 기존 Transformer 아키텍처에 대한 기본적인 지식을 숙지하는 것이 좋습니다. 인코더, 디코더 및 어텐션의 작동 방식을 알면 다양한 Transformer 모델이 어떻게 작동하는지 이해하는 데 도움이 됩니다. 시작 단계거나 복습이 필요한 경우, 더 많은 정보를 위해 [코스](https://huggingface.co/course/chapter1/4?fw=pt)를 확인하세요!
+
+
+
+## 음성 및 오디오[[speech-and-audio]]
+
+[Wav2Vec2](model_doc/wav2vec2)는 레이블이 지정되지 않은 음성 데이터에 대해 사전훈련된 모델로, 오디오 분류 및 자동 음성 인식을 위해 레이블이 지정된 데이터로 미세 조정합니다.
+
+
+
+
+
+이 모델에는 4가지 주요 구성 요소가 있습니다:
+
+1. *특징 인코더(feature encoder)*는 원시 오디오 파형(raw audio waveform)을 가져와서 제로 평균 및 단위 분산으로 표준화하고, 각각 20ms 길이의 특징 벡터의 시퀀스로 변환합니다.
+
+2. 오디오 파형은 본질적으로 연속적이기 때문에, 텍스트 시퀀스를 단어로 나누는 것과 같이 분할할 수 없습니다. 그래서 *양자화 모듈(quantization module)*로 전달되는 특징 벡터는 이산형 음성 단위를 학습하기 위한 것입니다. 음성 단위는 *코드북(codebook)*(어휘집이라고 생각할 수 있습니다)이라는 코드단어(codewords) 콜렉션에서 선택됩니다. 코드북에서 연속적인 오디오 입력을 가장 잘 나타내는 벡터 또는 음성 단위가 선택되어 모델을 통과합니다.
+
+3. 특징 벡터의 절반은 무작위로 마스크가 적용되며, 마스크된 특징 벡터는 *상대적 위치 임베딩*을 추가하는 Transformer 인코더인 *문맥 네트워크(context network)*로 전달됩니다.
+
+4. 문맥 네트워크의 사전훈련 목표는 *대조적 작업(contrastive task)*입니다. 모델은 잘못된 예측 시퀀스에서 마스크된 예측의 실제 양자화된 음성 표현을 예측하며, 모델이 가장 유사한 컨텍스트 벡터와 양자화된 음성 단위(타겟 레이블)를 찾도록 권장합니다.
+
+이제 wav2vec2가 사전훈련되었으므로, 오디오 분류 또는 자동 음성 인식을 위해 데이터에 맞춰 미세 조정할 수 있습니다!
+
+### 오디오 분류[[audio-classification]]
+
+사전훈련된 모델을 오디오 분류에 사용하려면, 기본 Wav2Vec2 모델 상단에 시퀀스 분류 헤드를 추가하면 됩니다. 분류 헤드는 인코더의 은닉 상태(hidden states)를 받는 선형 레이어입니다. 은닉 상태는 각각 길이가 다른 오디오 프레임에서 학습된 특징을 나타냅니다. 고정 길이의 벡터 하나를 만들기 위해, 은닉 상태는 먼저 풀링되고, 클래스 레이블에 대한 로짓으로 변환됩니다. 가장 가능성이 높은 클래스를 찾기 위해 로짓과 타겟 사이의 교차 엔트로피 손실이 계산됩니다.
+
+오디오 분류에 직접 도전할 준비가 되셨나요? 완전한 [오디오 분류 가이드](tasks/audio_classification)를 확인하여 Wav2Vec2를 미세 조정하고 추론에 사용하는 방법을 학습하세요!
+
+### 자동 음성 인식[[automatic-speech-recognition]]
+
+사전훈련된 모델을 자동 음성 인식에 사용하려면, [연결주의적 시간 분류(CTC, Connectionist Temporal Classification)](glossary#connectionist-temporal-classification-ctc)를 위해 기본 Wav2Vec2 모델 상단에 언어 모델링 헤드를 추가합니다. 언어 모델링 헤드는 인코더의 은닉 상태를 받아서 로짓으로 변환합니다. 각 로짓은 토큰 클래스(토큰 수는 작업의 어휘에서 나타납니다)를 나타냅니다. CTC 손실은 텍스트로 디코딩된 토큰에서 가장 가능성이 높은 토큰 시퀀스를 찾기 위해 로짓과 타겟 사이에서 계산됩니다.
+
+자동 음성 인식에 직접 도전할 준비가 되셨나요? 완전한 [자동 음성 인식 가이드](tasks/asr)를 확인하여 Wav2Vec2를 미세 조정하고 추론에 사용하는 방법을 학습하세요!
+
+## 컴퓨터 비전[[computer-vision]]
+
+컴퓨터 비전 작업에 접근하는 2가지 방법이 있습니다:
+
+1. 이미지를 패치 시퀀스로 분리하고 Transformer로 병렬 처리합니다.
+2. [ConvNeXT](model_doc/convnext)와 같은 현대 CNN을 사용합니다. 이는 합성곱 레이어를 기반으로 하지만 현대 네트워크 설계를 적용합니다.
+
+
+
+세 번째 방법은 Transformer와 합성곱(예를 들어, [Convolutional Vision Transformer](model_doc/cvt) 또는 [LeViT](model_doc/levit))을 결합하는 것입니다. 우리는 살펴볼 두 가지 방법만 결합하기 때문에 여기서 이 방법을 다루지 않습니다.
+
+
+
+ViT와 ConvNeXT는 일반적으로 이미지 분류에서 사용되지만, 물체 감지, 분할, 깊이 추정과 같은 다른 비전 작업에는 각각 DETR, Mask2Former, GLPN이 더 적합하므로 이러한 모델을 살펴보겠습니다.
+
+### 이미지 분류[[image-classification]]
+
+ViT와 ConvNeXT 모두 이미지 분류에 사용될 수 있지만, ViT는 어텐션 메커니즘을, ConvNeXT는 합성곱을 사용하는 것이 주된 차이입니다.
+
+#### Transformer[[transformer]]
+
+[ViT](model_doc/vit)은 합성곱을 전적으로 순수 Transformer 아키텍처로 대체합니다. 기존 Transformer에 익숙하다면, ViT를 이해하는 방법의 대부분을 이미 파악했다고 볼 수 있습니다.
+
+
+
+
+
+ViT가 도입한 주요 변경 사항은 이미지가 Transformer로 어떻게 전달되는지에 있습니다:
+
+1. 이미지는 서로 중첩되지 않는 정사각형 패치로 분할되고, 각 패치는 벡터 또는 *패치 임베딩(patch embedding)*으로 변환됩니다. 패치 임베딩은 적절한 입력 차원을 만드는 2D 합성곱 계층에서 생성됩니다(기본 Transformer의 경우 각 패치의 임베딩마다 768개의 값이 필요합니다). 224x224 픽셀 이미지가 있다면, 16x16 이미지 패치 196개로 분할할 수 있습니다. 텍스트가 단어로 토큰화되는 것처럼, 이미지도 패치 시퀀스로 "토큰화"됩니다.
+
+2. *학습 가능한 임베딩(learnable embedding)*(특수한 `[CLS]` 토큰)이 BERT와 같이 패치 임베딩의 시작 부분에 추가됩니다. `[CLS]` 토큰의 마지막 은닉 상태는 부착된 분류 헤드의 입력으로 사용되고, 다른 출력은 무시됩니다. 이 토큰은 모델이 이미지의 표현을 인코딩하는 방법을 학습하는 데 도움이 됩니다.
+
+3. 패치와 학습 가능한 임베딩에 마지막으로 추가할 것은 *위치 임베딩*입니다. 왜냐하면 모델은 이미지 패치의 순서를 모르기 때문입니다. 위치 임베딩도 학습 가능하며, 패치 임베딩과 동일한 크기를 가집니다. 최종적으로, 모든 임베딩이 Transformer 인코더에 전달됩니다.
+
+4. `[CLS]` 토큰을 포함한 출력은 다층 퍼셉트론 헤드(MLP)에 전달됩니다. ViT의 사전훈련 목표는 단순히 분류입니다. 다른 분류 헤드와 같이, MLP 헤드는 출력을 클래스 레이블에 대해 로짓으로 변환하고 교차 엔트로피 손실을 계산하여 가장 가능성이 높은 클래스를 찾습니다.
+
+이미지 분류에 직접 도전할 준비가 되셨나요? 완전한 [이미지 분류 가이드](tasks/image_classification)를 확인하여 ViT를 미세 조정하고 추론에 사용하는 방법을 학습하세요!
+
+#### CNN[[cnn]]
+
+
+
+이 섹션에서는 합성곱에 대해 간략하게 설명합니다. 그러나 이미지의 모양과 크기가 어떻게 변화하는지에 대한 사전 이해가 있다면 도움이 될 것입니다. 합성곱에 익숙하지 않은 경우, fastai book의 [합성곱 신경망 챕터](https://github.com/fastai/fastbook/blob/master/13_convolutions.ipynb)를 확인하세요!
+
+
+
+[ConvNeXT](model_doc/convnext)는 성능을 높이기 위해 새로운 현대 네트워크 설계를 적용한 CNN 구조입니다. 그러나 합성곱은 여전히 모델의 핵심입니다. 높은 수준의 관점에서 볼 때, [합성곱](glossary#convolution)은 작은 행렬(*커널*)에 이미지 픽셀의 작은 윈도우를 곱하는 연산입니다. 이는 특정 텍스쳐(texture)이나 선의 곡률과 같은 일부 특징을 계산합니다. 그러고 다음 픽셀 윈도우로 넘어가는데, 여기서 합성곱이 이동하는 거리를 *보폭(stride)*이라고 합니다.
+
+
+
+
+
+패딩이나 보폭이 없는 기본 합성곱, 딥러닝을 위한 합성곱 연산 가이드
+
+이 출력을 다른 합성곱 레이어에 전달할 수 있으며, 각 연속적인 레이어를 통해 네트워크는 핫도그나 로켓과 같이 더 복잡하고 추상적인 것을 학습합니다. 합성곱 레이어 사이에 풀링 레이어를 추가하여 차원을 줄이고 특징의 위치 변화에 대해 모델을 더 견고하게 만드는 것이 일반적입니다.
+
+
+
+
+
+ConvNeXT는 CNN을 5가지 방식으로 현대화합니다:
+
+1. 각 단계의 블록 수를 변경하고 더 큰 보폭과 그에 대응하는 커널 크기로 이미지를 "패치화(patchify)"합니다. 겹치지 않는 슬라이딩 윈도우는 ViT가 이미지를 패치로 분할하는 방법과 유사하게 이 패치화 전략을 만듭니다.
+
+2. *병목(bottleneck)* 레이어는 채널 수를 줄였다가 다시 복원합니다. 왜냐하면 1x1 합성곱을 수행하는 것이 더 빠르고, 깊이를 늘릴 수 있기 때문입니다. 역 병목(inverted bottlenect)은 채널 수를 확장하고 축소함으로써 그 반대로 수행하므로, 메모리 효율이 더 높습니다.
+
+3. 병목 레이어의 일반적인 3x3 합성곱 레이어를 각 입력 채널에 개별적으로 합성곱을 적용한 다음 마지막에 쌓는 *깊이별 합성곱(depthwise convolution)*으로 대체합니다. 이는 네트워크 폭이 넓혀 성능이 향상됩니다.
+
+4. ViT는 어텐션 메커니즘 덕분에 한 번에 더 많은 이미지를 볼 수 있는 전역 수신 필드를 가지고 있습니다. ConvNeXT는 커널 크기를 7x7로 늘려 이 효과를 재현하려고 시도합니다.
+
+5. 또한 ConvNeXT는 Transformer 모델을 모방하는 몇 가지 레이어 설계를 변경합니다. 활성화 및 정규화 레이어가 더 적고, 활성화 함수가 ReLU 대신 GELU로 전환되고, BatchNorm 대신 LayerNorm을 사용합니다.
+
+합성곱 블록의 출력은 분류 헤드로 전달되며, 분류 헤드는 출력을 로짓으로 변환하고 교차 엔트로피 손실을 계산하여 가장 가능성이 높은 레이블을 찾습니다.
+
+### 객체 탐지[[object-detection]]
+
+[DETR](model_doc/detr), *DEtection TRansformer*는 CNN과 Transformer 인코더-디코더를 결합한 종단간(end-to-end) 객체 탐지 모델입니다.
+
+
+
+
+
+1. 사전훈련된 CNN *백본(backbone)*은 픽셀 값으로 나타낸 이미지를 가져와 저해상도 특징 맵을 만듭니다. 특징 맵에 대해 1x1 합성곱을 적용하여 차원을 줄이고, 고수준 이미지 표현을 가진 새로운 특징 맵을 생성합니다. Transformer는 시퀀스 모델이기 때문에 특징 맵을 위치 임베딩과 결합된 특징 벡터의 시퀀스로 평탄화합니다.
+
+2. 특징 벡터는 어텐션 레이어를 사용하여 이미지 표현을 학습하는 인코더에 전달됩니다. 다음으로, 인코더의 은닉 상태는 디코더에서 *객체 쿼리*와 결합됩니다. 객체 쿼리는 이미지의 다른 영역에 초점을 맞춘 학습된 임베딩으로 학습되고, 각 어텐션 레이어를 진행하면서 갱신됩니다. 디코더의 은닉 상태는 각 객체 쿼리에 대한 바운딩 박스 좌표와 클래스 레이블을 예측하는 순방향 네트워크에 전달되며, 객체가 없는 경우 `no object`가 출력됩니다.
+
+ DETR은 각 객체 쿼리를 병렬로 디코딩하여 *N* 개의 최종 예측을 출력합니다. 여기서 *N*은 쿼리 수입니다. 한 번에 하나의 요소를 예측하는 일반적인 자기회귀 모델과 달리, 객체 탐지는 한 번에 *N* 개의 예측을 수행하는 집합 예측 작업(`바운딩 박스`, `클래스 레이블`)입니다.
+
+3. DETR은 훈련 중 *이분 매칭 손실(bipartite matching loss)*을 사용하여 고정된 수의 예측과 고정된 실제 정답 레이블(ground truth labels) 세트를 비교합니다. *N*개의 레이블 세트에 실제 정답 레이블보다 적은 경우, `no object` 클래스로 패딩됩니다. 이 손실 함수는 DETR이 예측과 실제 정답 레이블 간 1:1 대응을 찾도록 권장합니다. 바운딩 박스 또는 클래스 레이블 중 하나라도 잘못된 경우, 손실이 발생합니다. 마찬가지로, 존재하지 않는 객체를 예측하는 경우, 패널티를 받습니다. 이로 인해 DETR은 이미지에서 눈에 잘 띄는 물체 하나에 집중하는 대신, 다른 객체를 찾도록 권장됩니다.
+
+객체 탐지 헤드가 DETR 상단에 추가되어 클래스 레이블과 바운딩 박스의 좌표를 찾습니다. 객체 탐지 헤드에는 두 가지 구성 요소가 있습니다: 디코더 은닉 상태를 클래스 레이블의 로짓으로 변환하는 선형 레이어 및 바운딩 박스를 예측하는 MLP
+
+객체 탐지에 직접 도전할 준비가 되셨나요? 완전한 [객체 탐지 가이드](tasks/object_detection)를 확인하여 DETR을 미세 조정하고 추론에 사용하는 방법을 학습하세요!
+
+### 이미지 분할[[image-segmentation]]
+
+[Mask2Former](model_doc/mask2former)는 모든 유형의 이미지 분할 작업을 해결하는 범용 아키텍처입니다. 전통적인 분할 모델은 일반적으로 시멘틱(semantic) 또는 파놉틱(panoptic) 분할과 같은 이미지 분할의 특정 하위 작업에 맞춰 조정됩니다. Mask2Former는 모든 작업을 *마스크 분류* 문제로 구성합니다. 마스크 분류는 픽셀을 *N*개 세그먼트로 그룹화하고, 주어진 이미지에 대해 *N*개의 마스크와 그에 대응하는 클래스 레이블을 예측합니다. 이 섹션에서 Mask2Former의 작동 방법을 설명한 다음, 마지막에 SegFormer를 미세 조정해볼 수 있습니다.
+
+
+
+
+
+Mask2Former에는 3가지 주요 구성 요소가 있습니다:
+
+1. [Swin](model_doc/swin) 백본이 이미지를 받아 3개의 연속된 3x3 합성곱에서 저해상도 이미지 특징 맵을 생성합니다.
+
+2. 특징 맵은 *픽셀 디코더*에 전달됩니다. 이 디코더는 저해상도 특징을 고해상도 픽셀 임베딩으로 점진적으로 업샘플링합니다. 픽셀 디코더는 실제로 원본 이미지의 1/32, 1/16, 1/8 해상도의 다중 스케일 특징(저해상도 및 고해상도 특징 모두 포함)을 생성합니다.
+
+3. 이러한 서로 다른 크기의 특징 맵은 고해상도 특징에서 작은 객체를 포착하기 위해 한 번에 하나의 Transformer 디코더 레이어에 연속적으로 공급됩니다. Mask2Former의 핵심은 디코더의 *마스크 어텐션* 메커니즘입니다. 전체 이미지를 참조할 수 있는 크로스 어텐션(cross-attention)과 달리, 마스크 어텐션은 이미지의 특정 영역에만 집중합니다. 이는 이미지의 지역적 특징만으로 모델이 충분히 학습할 수 있기 때문에 더 빠르고 성능이 우수합니다.
+
+4. [DETR](tasks_explained#object-detection)과 같이, Mask2Former는 학습된 객체 쿼리를 사용하고 이를 픽셀 디코더에서의 이미지 특징과 결합하여 예측 집합(`클래스 레이블`, `마스크 예측`)을 생성합니다. 디코더의 은닉 상태는 선형 레이어로 전달되어 클래스 레이블에 대한 로짓으로 변환됩니다. 로짓과 클래스 레이블 사이의 교차 엔트로피 손실을 계산하여 가장 가능성이 높은 것을 찾습니다.
+
+ 마스크 예측은 픽셀 임베딩과 최종 디코더 은닉 상태를 결합하여 생성됩니다. 시그모이드 교차 엔트로피 및 Dice 손실은 로짓과 실제 정답 마스크(ground truth mask) 사이에서 계산되어 가장 가능성이 높은 마스크를 찾습니다.
+
+이미지 분할에 직접 도전할 준비가 되셨나요? 완전한 [이미지 분할 가이드](tasks/semantic_segmentation)를 확인하여 SegFormer를 미세 조정하고 추론에 사용하는 방법을 학습하세요!
+
+### 깊이 추정[[depth-estimation]]
+
+[GLPN](model_doc/glpn), *Global-Local Path Network*는 [SegFormer](model_doc/segformer) 인코더와 경량 디코더를 결합한 깊이 추정을 위한 Transformer입니다.
+
+
+
+
+
+1. ViT와 같이, 이미지는 패치 시퀀스로 분할되지만, 이미지 패치가 더 작다는 점이 다릅니다. 이는 세그멘테이션이나 깊이 추정과 같은 밀도 예측 작업에 더 적합합니다. 이미지 패치는 패치 임베딩으로 변환되어(패치 임베딩이 생성되는 방법은 [이미지 분류](#image-classification) 섹션을 참조하세요), 인코더로 전달됩니다.
+
+2. 인코더는 패치 임베딩을 받아, 여러 인코더 블록에 전달합니다. 각 블록은 어텐션 및 Mix-FFN 레이어로 구성됩니다. 후자의 목적은 위치 정보를 제공하는 것입니다. 각 인코더 블록의 끝에는 계층적 표현을 생성하기 위한 *패치 병합(patch merging)* 레이어가 있습니다. 각 인접한 패치 그룹의 특징은 연결되고, 연결된 특징에 선형 레이어가 적용되어 패치 수를 1/4의 해상도로 줄입니다. 이는 다음 인코더 블록의 입력이 되며, 이러한 전체 프로세스는 1/8, 1/16, 1/32 해상도의 이미지 특징을 가질 때까지 반복됩니다.
+
+3. 경량 디코더는 인코더에서 마지막 특징 맵(1/32 크기)을 가져와 1/16 크기로 업샘플링합니다. 여기서, 특징은 *선택적 특징 융합(SFF, Selective Feature Fusion)* 모듈로 전달됩니다. 이 모듈은 각 특징에 대해 어텐션 맵에서 로컬 및 전역 특징을 선택하고 결합한 다음, 1/8로 업샘플링합니다. 이 프로세스는 디코딩된 특성이 원본 이미지와 동일한 크기가 될 때까지 반복됩니다. 출력은 두 개의 합성곱 레이어를 거친 다음, 시그모이드 활성화가 적용되어 각 픽셀의 깊이를 예측합니다.
+
+## 자연어처리[[natural-language-processing]]
+
+Transformer는 초기에 기계 번역을 위해 설계되었고, 그 이후로는 사실상 모든 NLP 작업을 해결하기 위한 기본 아키텍처가 되었습니다. 어떤 작업은 Transformer의 인코더 구조에 적합하며, 다른 작업은 디코더에 더 적합합니다. 또 다른 작업은 Transformer의 인코더-디코더 구조를 모두 활용합니다.
+
+### 텍스트 분류[[text-classification]]
+
+[BERT](model_doc/bert)는 인코더 전용 모델이며, 텍스트의 풍부한 표현을 학습하기 위해 양방향의 단어에 주목함으로써 심층 양방향성(deep bidirectionality)을 효과적으로 구현한 최초의 모델입니다.
+
+1. BERT는 [WordPiece](tokenizer_summary#wordpiece) 토큰화를 사용하여 문장의 토큰 임베딩을 생성합니다. 단일 문장과 한 쌍의 문장을 구분하기 위해 특수한 `[SEP]` 토큰이 추가됩니다. 모든 텍스트 시퀀스의 시작 부분에는 특수한 `[CLS]` 토큰이 추가됩니다. `[CLS]` 토큰이 있는 최종 출력은 분류 작업을 위한 분류 헤드로 입력에 사용됩니다. BERT는 또한 한 쌍의 문장에서 각 토큰이 첫 번째 문장인지 두 번째 문장에 속하는지 나타내는 세그먼트 임베딩(segment embedding)을 추가합니다.
+
+2. BERT는 마스크드 언어 모델링과 다음 문장 예측, 두 가지 목적으로 사전훈련됩니다. 마스크드 언어 모델링에서는 입력 토큰의 일부가 무작위로 마스킹되고, 모델은 이를 예측해야 합니다. 이는 모델이 모든 단어를 보고 다음 단어를 "예측"할 수 있는 양방향성 문제를 해결합니다. 예측된 마스크 토큰의 최종 은닉 상태는 어휘에 대한 소프트맥스가 있는 순방향 네트워크로 전달되어 마스크된 단어를 예측합니다.
+
+ 두 번째 사전훈련 대상은 다음 문장 예측입니다. 모델은 문장 B가 문장 A 다음에 오는지 예측해야 합니다. 문장 B가 다음 문장인 경우와 무작위 문장인 경우 각각 50%의 확률로 발생합니다. 다음 문장인지 아닌지에 대한 예측은 두 개의 클래스(`IsNext` 및 `NotNext`)에 대한 소프트맥스가 있는 순방향 네트워크로 전달됩니다.
+
+3. 입력 임베딩은 여러 인코더 레이어를 거쳐서 최종 은닉 상태를 출력합니다.
+
+사전훈련된 모델을 텍스트 분류에 사용하려면, 기본 BERT 모델 상단에 시퀀스 분류 헤드를 추가합니다. 시퀀스 분류 헤드는 최종 은닉 상태를 받는 선형 레이어이며, 로짓으로 변환하기 위해 선형 변환을 수행합니다. 교차 엔트로피 손실은 로짓과 타겟 간에 계산되어 가장 가능성이 높은 레이블을 찾습니다.
+
+텍스트 분류에 직접 도전할 준비가 되셨나요? 완전한 [텍스트 분류 가이드](tasks/sequence_classification)를 확인하여 DistilBERT를 미세 조정하고 추론에 사용하는 방법을 학습하세요!
+
+### 토큰 분류[[token-classification]]
+
+개체명 인식(Named Entity Recognition, NER)과 같은 토큰 분류 작업에 BERT를 사용하려면, 기본 BERT 모델 상단에 토큰 분류 헤드를 추가합니다. 토큰 분류 헤드는 최종 은닉 상태를 받는 선형 레이어이며, 로짓으로 변환하기 위해 선형 변환을 수행합니다. 교차 엔트로피 손실은 로짓과 각 토큰 간에 계산되어 가장 가능성이 높은 레이블을 찾습니다.
+
+토큰 분류에 직접 도전할 준비가 되셨나요? 완전한 [토큰 분류 가이드](tasks/token_classification)를 확인하여 DistilBERT를 미세 조정하고 추론에 사용하는 방법을 학습하세요!
+
+### 질의응답[[question-answering]]
+
+질의응답에 BERT를 사용하려면, 기본 BERT 모델 위에 스팬(span) 분류 헤드를 추가합니다. 이 선형 레이어는 최종 은닉 상태를 받고, 답변에 대응하는 `스팬`의 시작과 끝 로그를 계산하기 위해 선형 변환을 수행합니다. 교차 엔트로피 손실은 로짓과 각 레이블 위치 간에 계산되어 답변에 대응하는 가장 가능성이 높은 텍스트의 스팬을 찾습니다.
+
+질의응답에 직접 도전할 준비가 되셨나요? 완전한 [질의응답 가이드](tasks/question_answering)를 확인하여 DistilBERT를 미세 조정하고 추론에 사용하는 방법을 학습하세요!
+
+
+
+💡 사전훈련된 BERT를 다양한 작업에 사용하는 것이 얼마나 쉬운지 주목하세요. 사전훈련된 모델에 특정 헤드를 추가하기만 하면 은닉 상태를 원하는 출력으로 조작할 수 있습니다!
+
+
+
+### 텍스트 생성[[text-generation]]
+
+[GPT-2](model_doc/gpt2)는 대량의 텍스트에 대해 사전훈련된 디코딩 전용 모델입니다. 프롬프트를 주어지면 설득력 있는 (항상 사실은 아니지만!) 텍스트를 생성하고 명시적으로 훈련되지 않았음에도 불구하고 질의응답과 같은 다른 NLP 작업을 완수할 수 있습니다.
+
+
+
+
+
+1. GPT-2는 단어를 토큰화하고 토큰 임베딩을 생성하기 위해 [바이트 페어 인코딩(BPE, byte pair encoding)](tokenizer_summary#bytepair-encoding-bpe)을 사용합니다. 위치 인코딩은 시퀀스에서 각 토큰의 위치를 나타내기 위해 토큰 임베딩에 추가됩니다. 입력 임베딩은 여러 디코더 블록을 거쳐 일부 최종 은닉 상태를 출력합니다. 각 디코더 블록 내에서 GPT-2는 *마스크드 셀프 어텐션(masked self-attention)* 레이어를 사용합니다. 이는 GPT-2가 이후 토큰(future tokens)에 주의를 기울일 수 없도록 합니다. 왼쪽에 있는 토큰에만 주의를 기울일 수 있습니다. 마스크드 셀프 어텐션에서는 어텐션 마스크를 사용하여 이후 토큰에 대한 점수(score)를 `0`으로 설정하기 때문에 BERT의 [`mask`] 토큰과 다릅니다.
+
+2. 디코더의 출력은 언어 모델링 헤드에 전달되며, 언어 모델링 헤드는 은닉 상태를 로짓으로 선형 변환을 수행합니다. 레이블은 시퀀스의 다음 토큰으로, 로짓을 오른쪽으로 하나씩 이동하여 생성됩니다. 교차 엔트로피 손실은 이동된 로짓과 레이블 간에 계산되어 가장 가능성이 높은 다음 토큰을 출력합니다.
+
+GPT-2의 사전훈련 목적은 전적으로 [인과적 언어 모델링](glossary#causal-language-modeling)에 기반하여, 시퀀스에서 다음 단어를 예측하는 것입니다. 이는 GPT-2가 텍스트 생성에 관련된 작업에 특히 우수하도록 합니다.
+
+텍스트 생성에 직접 도전할 준비가 되셨나요? 완전한 [인과적 언어 모델링 가이드](tasks/language_modeling#causal-language-modeling)를 확인하여 DistilGPT-2를 미세 조정하고 추론에 사용하는 방법을 학습하세요!
+
+
+
+텍스트 생성에 대한 자세한 내용은 [텍스트 생성 전략](generation_strategies) 가이드를 확인하세요!
+
+
+
+### 요약[[summarization]]
+
+[BART](model_doc/bart) 및 [T5](model_doc/t5)와 같은 인코더-디코더 모델은 요약 작업의 시퀀스-투-시퀀스 패턴을 위해 설계되었습니다. 이 섹션에서 BART의 작동 방법을 설명한 다음, 마지막에 T5를 미세 조정해볼 수 있습니다.
+
+
+
+
+
+1. BART의 인코더 아키텍처는 BERT와 매우 유사하며 텍스트의 토큰 및 위치 임베딩을 받습니다. BART는 입력을 변형시키고 디코더로 재구성하여 사전훈련됩니다. 특정 변형 기법이 있는 다른 인코더와는 달리, BART는 모든 유형의 변형을 적용할 수 있습니다. 그러나 *text infilling* 변형 기법이 가장 잘 작동합니다. Text Infiling에서는 여러 텍스트 스팬을 **단일** [`mask`] 토큰으로 대체합니다. 이는 모델이 마스크된 토큰을 예측해야 하고, 모델에 누락된 토큰의 수를 예측하도록 가르치기 때문에 중요합니다. 입력 임베딩과 마스크된 스팬이 인코더를 거쳐 최종 은닉 상태를 출력하지만, BERT와 달리 BART는 마지막에 단어를 예측하는 순방향 네트워크를 추가하지 않습니다.
+
+2. 인코더의 출력은 디코더로 전달되며, 디코더는 인코더의 출력에서 마스크 토큰과 변형되지 않은 토큰을 예측해야 합니다. 이는 디코더가 원본 텍스트를 복원하는 데 도움이 되는 추가적인 문맥을 얻도록 합니다. 디코더의 출력은 언어 모델링 헤드에 전달되며, 언어 모델링 헤드는 은닉 상태를 로짓으로 선형 변환을 수행합니다. 교차 엔트로피 손실은 로짓과 토큰이 오른쪽으로 이동된 레이블 간에 계산됩니다.
+
+요약에 직접 도전할 준비가 되셨나요? 완전한 [요약 가이드](tasks/summarization)를 확인하여 T5를 미세 조정하고 추론에 사용하는 방법을 학습하세요!
+
+
+
+텍스트 생성에 대한 자세한 내용은 [텍스트 생성 전략](generation_strategies) 가이드를 확인하세요!
+
+
+
+### 번역[[translation]]
+
+번역은 시퀀스-투-시퀀스 작업의 또 다른 예로, [BART](model_doc/bart) 또는 [T5](model_doc/t5)와 같은 인코더-디코더 모델을 사용할 수 있습니다. 이 섹션에서 BART의 작동 방법을 설명한 다음, 마지막에 T5를 미세 조정해볼 수 있습니다.
+
+BART는 원천 언어를 타겟 언어로 디코딩할 수 있는 입력에 매핑하기 위해 무작위로 초기화된 별도의 인코더를 추가하여 번역에 적용합니다. 이 새로운 인코더의 임베딩은 원본 단어 임베딩 대신 사전훈련된 인코더로 전달됩니다. 원천 인코더는 모델 출력의 교차 엔트로피 손실로부터 원천 인코더, 위치 임베딩, 입력 임베딩을 갱신하여 훈련됩니다. 첫 번째 단계에서는 모델 파라미터가 고정되고, 두 번째 단계에서는 모든 모델 파라미터가 함께 훈련됩니다.
+
+BART는 이후 번역을 위해 다양한 언어로 사전훈련된 다국어 버전의 mBART로 확장되었습니다.
+
+번역에 직접 도전할 준비가 되셨나요? 완전한 [번역 가이드](tasks/summarization)를 확인하여 T5를 미세 조정하고 추론에 사용하는 방법을 학습하세요!
+
+
+
+텍스트 생성에 대한 자세한 내용은 [텍스트 생성 전략](generation_strategies) 가이드를 확인하세요!
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/testing.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/testing.md
new file mode 100644
index 0000000000000000000000000000000000000000..fd3f548eeb812910fda5c0040ceb8cb6710538e0
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/testing.md
@@ -0,0 +1,1278 @@
+
+
+# 테스트[[testing]]
+
+
+먼저 🤗 Transformers 모델이 어떻게 테스트되는지 살펴보고, 새로운 테스트를 작성 및 기존 테스트를 개선하는 방법을 알아봅시다.
+
+이 저장소에는 2개의 테스트 스위트가 있습니다:
+
+1. `tests` - 일반 API에 대한 테스트
+2. `examples` - API의 일부가 아닌 다양한 응용 프로그램에 대한 테스트
+
+## Transformers 테스트 방법[[how-transformers-are-tested]]
+
+1. PR이 제출되면 9개의 CircleCi 작업으로 테스트가 진행됩니다. 해당 PR에 대해 새로운 커밋이 생성될 때마다 테스트는 다시 진행됩니다. 이 작업들은
+ 이 [config 파일](https://github.com/huggingface/transformers/tree/main/.circleci/config.yml)에 정의되어 있으므로 필요하다면
+ 사용자의 로컬 환경에서 동일하게 재현해 볼 수 있습니다.
+
+ 이 CI 작업은 `@slow` 테스트를 실행하지 않습니다.
+
+2. [github actions](https://github.com/huggingface/transformers/actions)에 의해 실행되는 작업은 3개입니다:
+
+ - [torch hub integration](https://github.com/huggingface/transformers/tree/main/.github/workflows/github-torch-hub.yml):
+ torch hub integration이 작동하는지 확인합니다.
+
+ - [self-hosted (push)](https://github.com/huggingface/transformers/tree/main/.github/workflows/self-push.yml): `main` 브랜치에서 커밋이 업데이트된 경우에만 GPU를 이용한 빠른 테스트를 실행합니다.
+ 이는 `src`, `tests`, `.github` 폴더 중 하나에 코드가 업데이트된 경우에만 실행됩니다.
+ (model card, notebook, 기타 등등을 추가한 경우 실행되지 않도록 하기 위해서입니다)
+
+ - [self-hosted runner](https://github.com/huggingface/transformers/tree/main/.github/workflows/self-scheduled.yml): `tests` 및 `examples`에서
+ GPU를 이용한 일반 테스트, 느린 테스트를 실행합니다.
+
+
+```bash
+RUN_SLOW=1 pytest tests/
+RUN_SLOW=1 pytest examples/
+```
+
+ 결과는 [여기](https://github.com/huggingface/transformers/actions)에서 확인할 수 있습니다.
+
+
+## 테스트 실행[[running-tests]]
+
+
+
+
+
+### 실행할 테스트 선택[[choosing-which-tests-to-run]]
+
+이 문서는 테스트를 실행하는 다양한 방법에 대해 자세히 설명합니다.
+모든 내용을 읽은 후에도, 더 자세한 내용이 필요하다면 [여기](https://docs.pytest.org/en/latest/usage.html)에서 확인할 수 있습니다.
+
+다음은 가장 유용한 테스트 실행 방법 몇 가지입니다.
+
+모두 실행:
+
+```console
+pytest
+```
+
+또는:
+
+```bash
+make test
+```
+
+후자는 다음과 같이 정의됩니다:
+
+```bash
+python -m pytest -n auto --dist=loadfile -s -v ./tests/
+```
+
+위의 명령어는 pytest에게 아래의 내용을 전달합니다:
+
+- 사용 가능한 CPU 코어 수만큼 테스트 프로세스를 실행합니다. (RAM이 충분하지 않다면, 테스트 프로세스 수가 너무 많을 수 있습니다!)
+- 동일한 파일의 모든 테스트는 동일한 테스트 프로세스에서 실행되어야 합니다.
+- 출력을 캡처하지 않습니다.
+- 자세한 모드로 실행합니다.
+
+
+
+### 모든 테스트 목록 가져오기[[getting-the-list-of-all-tests]]
+
+테스트 스위트의 모든 테스트:
+
+```bash
+pytest --collect-only -q
+```
+
+지정된 테스트 파일의 모든 테스트:
+
+```bash
+pytest tests/test_optimization.py --collect-only -q
+```
+
+### 특정 테스트 모듈 실행[[run-a-specific-test-module]]
+
+개별 테스트 모듈 실행하기:
+
+```bash
+pytest tests/utils/test_logging.py
+```
+
+### 특정 테스트 실행[[run-specific-tests]]
+
+대부분의 테스트 내부에서는 unittest가 사용됩니다. 따라서 특정 하위 테스트를 실행하려면 해당 테스트를 포함하는 unittest 클래스의 이름을 알아야 합니다.
+예를 들어 다음과 같을 수 있습니다:
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest::test_adam_w
+```
+
+위의 명령어의 의미는 다음과 같습니다:
+
+- `tests/test_optimization.py` - 테스트가 있는 파일
+- `OptimizationTest` - 클래스의 이름
+- `test_adam_w` - 특정 테스트 함수의 이름
+
+파일에 여러 클래스가 포함된 경우, 특정 클래스의 테스트만 실행할 수도 있습니다. 예를 들어 다음과 같습니다:
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest
+```
+
+이 명령어는 해당 클래스 내부의 모든 테스트를 실행합니다.
+
+앞에서 언급한 것처럼 `OptimizationTest` 클래스에 포함된 테스트를 확인할 수 있습니다.
+
+```bash
+pytest tests/test_optimization.py::OptimizationTest --collect-only -q
+```
+
+키워드 표현식을 사용하여 테스트를 실행할 수도 있습니다.
+
+`adam`이라는 이름을 포함하는 테스트만 실행하려면 다음과 같습니다:
+
+```bash
+pytest -k adam tests/test_optimization.py
+```
+
+논리 연산자 `and`와 `or`를 사용하여 모든 키워드가 일치해야 하는지 또는 어느 하나가 일치해야 하는지를 나타낼 수 있습니다.
+`not`은 부정할 때 사용할 수 있습니다.
+
+`adam`이라는 이름을 포함하지 않는 모든 테스트를 실행하려면 다음과 같습니다:
+
+```bash
+pytest -k "not adam" tests/test_optimization.py
+```
+
+두 가지 패턴을 하나로 결합할 수도 있습니다:
+
+```bash
+pytest -k "ada and not adam" tests/test_optimization.py
+```
+
+예를 들어 `test_adafactor`와 `test_adam_w`를 모두 실행하려면 다음을 사용할 수 있습니다:
+
+```bash
+pytest -k "test_adam_w or test_adam_w" tests/test_optimization.py
+```
+
+여기서 `or`를 사용하는 것에 유의하세요. 두 키워드 중 하나가 일치하도록 하기 위한 목적으로 사용하기 때문입니다.
+
+두 패턴이 모두 포함되어야 하는 테스트만 실행하려면, `and`를 사용해야 합니다:
+
+```bash
+pytest -k "test and ada" tests/test_optimization.py
+```
+
+### `accelerate` 테스트 실행[[run-`accelerate`-tests]]
+
+모델에서 `accelerate` 테스트를 실행해야 할 때가 있습니다. 이를 위해서는 명령어에 `-m accelerate_tests`를 추가하면 됩니다.
+예를 들어, `OPT`에서 이러한 테스트를 실행하려면 다음과 같습니다:
+```bash
+RUN_SLOW=1 pytest -m accelerate_tests tests/models/opt/test_modeling_opt.py
+```
+
+### 문서 테스트 실행[[run-documentation-tests]]
+
+예시 문서가 올바른지 테스트하려면 `doctests`가 통과하는지 확인해야 합니다.
+예를 들어, [`WhisperModel.forward`'s docstring](https://github.com/huggingface/transformers/blob/main/src/transformers/models/whisper/modeling_whisper.py#L1017-L1035)를 사용해 봅시다:
+
+```python
+r"""
+Returns:
+
+Example:
+ ```python
+ >>> import torch
+ >>> from transformers import WhisperModel, WhisperFeatureExtractor
+ >>> from datasets import load_dataset
+
+ >>> model = WhisperModel.from_pretrained("openai/whisper-base")
+ >>> feature_extractor = WhisperFeatureExtractor.from_pretrained("openai/whisper-base")
+ >>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+ >>> inputs = feature_extractor(ds[0]["audio"]["array"], return_tensors="pt")
+ >>> input_features = inputs.input_features
+ >>> decoder_input_ids = torch.tensor([[1, 1]]) * model.config.decoder_start_token_id
+ >>> last_hidden_state = model(input_features, decoder_input_ids=decoder_input_ids).last_hidden_state
+ >>> list(last_hidden_state.shape)
+ [1, 2, 512]
+ ```"""
+
+```
+
+원하는 파일의 모든 docstring 예제를 자동으로 테스트하려면 다음 명령을 실행하면 됩니다:
+```bash
+pytest --doctest-modules
+```
+파일의 확장자가 markdown인 경우 `--doctest-glob="*.md"` 인수를 추가해야 합니다.
+
+### 수정된 테스트만 실행[[run-only-modified-tests]]
+
+수정된 파일 또는 현재 브랜치 (Git 기준)와 관련된 테스트를 실행하려면 [pytest-picked](https://github.com/anapaulagomes/pytest-picked)을 사용할 수 있습니다.
+이는 변경한 내용이 테스트에 영향을 주지 않았는지 빠르게 확인할 수 있는 좋은 방법입니다.
+
+```bash
+pip install pytest-picked
+```
+
+```bash
+pytest --picked
+```
+
+수정되었지만, 아직 커밋되지 않은 모든 파일 및 폴더에서 테스트가 실행됩니다.
+
+### 소스 수정 시 실패한 테스트 자동 재실행[[automatically-rerun-failed-tests-on-source-modification]]
+
+[pytest-xdist](https://github.com/pytest-dev/pytest-xdist)는 모든 실패한 테스트를 감지하고,
+파일을 수정한 후에 파일을 계속 재실행하여 테스트가 성공할 때까지 기다리는 매우 유용한 기능을 제공합니다.
+따라서 수정한 내용을 확인한 후 pytest를 다시 시작할 필요가 없습니다.
+모든 테스트가 통과될 때까지 이 과정을 반복한 후 다시 전체 실행이 이루어집니다.
+
+```bash
+pip install pytest-xdist
+```
+
+재귀적 모드의 사용: `pytest -f` 또는 `pytest --looponfail`
+
+파일의 변경 사항은 `looponfailroots` 루트 디렉터리와 해당 내용을 (재귀적으로) 확인하여 감지됩니다.
+이 값의 기본값이 작동하지 않는 경우,
+`setup.cfg`의 설정 옵션을 변경하여 프로젝트에서 변경할 수 있습니다:
+
+```ini
+[tool:pytest]
+looponfailroots = transformers tests
+```
+
+또는 `pytest.ini`/`tox.ini`` 파일:
+
+```ini
+[pytest]
+looponfailroots = transformers tests
+```
+
+이렇게 하면 ini-file의 디렉터리를 기준으로 상대적으로 지정된 각 디렉터리에서 파일 변경 사항만 찾게 됩니다.
+
+
+이 기능을 대체할 수 있는 구현 방법인 [pytest-watch](https://github.com/joeyespo/pytest-watch)도 있습니다.
+
+
+### 특정 테스트 모듈 건너뛰기[[skip-a-test-module]]
+
+모든 테스트 모듈을 실행하되 특정 모듈을 제외하려면, 실행할 테스트 목록을 명시적으로 지정할 수 있습니다.
+예를 들어, `test_modeling_*.py` 테스트를 제외한 모든 테스트를 실행하려면 다음을 사용할 수 있습니다:
+
+```bash
+pytest *ls -1 tests/*py | grep -v test_modeling*
+```
+
+### 상태 초기화[[clearing state]]
+
+CI 빌드 및 (속도에 대한) 격리가 중요한 경우, 캐시를 지워야 합니다:
+
+```bash
+pytest --cache-clear tests
+```
+
+### 테스트를 병렬로 실행[[running-tests-in-parallel]]
+
+이전에 언급한 것처럼 `make test`는 테스트를 병렬로 실행하기 위해
+`pytest-xdist` 플러그인(`-n X` 인수, 예를 들어 `-n 2`를 사용하여 2개의 병렬 작업 실행)을 통해 실행됩니다.
+
+`pytest-xdist`의 `--dist=` 옵션을 사용하여 테스트를 어떻게 그룹화할지 제어할 수 있습니다.
+`--dist=loadfile`은 하나의 파일에 있는 테스트를 동일한 프로세스로 그룹화합니다.
+
+실행된 테스트의 순서가 다르고 예측할 수 없기 때문에, `pytest-xdist`로 테스트 스위트를 실행하면 실패가 발생할 수 있습니다 (검출되지 않은 결합된 테스트가 있는 경우).
+이 경우 [pytest-replay](https://github.com/ESSS/pytest-replay)를 사용하면 동일한 순서로 테스트를 다시 실행해서
+실패하는 시퀀스를 최소화하는 데에 도움이 됩니다.
+
+### 테스트 순서와 반복[[test-order-and-repetition]]
+
+잠재적인 종속성 및 상태 관련 버그(tear down)를 감지하기 위해
+테스트를 여러 번, 연속으로, 무작위로 또는 세트로 반복하는 것이 좋습니다.
+그리고 직접적인 여러 번의 반복은 DL의 무작위성에 의해 발견되는 일부 문제를 감지하는 데에도 유용합니다.
+
+
+#### 테스트를 반복[[repeat-tests]]
+
+- [pytest-flakefinder](https://github.com/dropbox/pytest-flakefinder):
+
+```bash
+pip install pytest-flakefinder
+```
+
+모든 테스트를 여러 번 실행합니다(기본값은 50번):
+
+```bash
+pytest --flake-finder --flake-runs=5 tests/test_failing_test.py
+```
+
+
+
+이 플러그인은 `pytest-xdist`의 `-n` 플래그와 함께 작동하지 않습니다.
+
+
+
+
+
+`pytest-repeat`라는 또 다른 플러그인도 있지만 `unittest`와 함께 작동하지 않습니다.
+
+
+
+#### 테스트를 임의의 순서로 실행[[run-tests-in-a-random-order]]
+
+```bash
+pip install pytest-random-order
+```
+
+중요: `pytest-random-order`가 설치되면 테스트가 자동으로 임의의 순서로 섞입니다.
+구성 변경이나 커맨드 라인 옵션이 필요하지 않습니다.
+
+앞서 설명한 것처럼 이를 통해 한 테스트의 상태가 다른 테스트의 상태에 영향을 미치는 결합된 테스트를 감지할 수 있습니다.
+`pytest-random-order`가 설치되면 해당 세션에서 사용된 랜덤 시드가 출력되며 예를 들어 다음과 같습니다:
+
+```bash
+pytest tests
+[...]
+Using --random-order-bucket=module
+Using --random-order-seed=573663
+```
+
+따라서 특정 시퀀스가 실패하는 경우에는 정확한 시드를 추가하여 재현할 수 있습니다. 예를 들어 다음과 같습니다:
+
+```bash
+pytest --random-order-seed=573663
+[...]
+Using --random-order-bucket=module
+Using --random-order-seed=573663
+```
+
+정확히 동일한 테스트 목록(또는 목록이 없음)을 사용하는 경우에만 정확한 순서를 재현합니다.
+목록을 수동으로 좁히기 시작하면 더 이상 시드에 의존할 수 없고 실패했던 정확한 순서로 수동으로 목록을 나열해야합니다. 그리고 `--random-order-bucket=none`을 사용하여 pytest에게 순서를 임의로 설정하지 않도록 알려야 합니다.
+예를 들어 다음과 같습니다:
+
+```bash
+pytest --random-order-bucket=none tests/test_a.py tests/test_c.py tests/test_b.py
+```
+
+모든 테스트에 대해 섞기를 비활성화하려면 다음과 같습니다:
+
+```bash
+pytest --random-order-bucket=none
+```
+
+기본적으로 `--random-order-bucket=module`이 내재되어 있으므로, 모듈 수준에서 파일을 섞습니다.
+또한 `class`, `package`, `global` 및 `none` 수준에서도 섞을 수 있습니다.
+자세한 내용은 해당 [문서](https://github.com/jbasko/pytest-random-order)를 참조하세요.
+
+또 다른 무작위화의 대안은 [`pytest-randomly`](https://github.com/pytest-dev/pytest-randomly)입니다.
+이 모듈은 매우 유사한 기능/인터페이스를 가지고 있지만, `pytest-random-order`에 있는 버킷 모드를 사용할 수는 없습니다.
+설치 후에는 자동으로 적용되는 문제도 동일하게 가집니다.
+
+### 외관과 느낌을 변경[[look-and-feel-variations]
+
+#### pytest-sugar 사용[[pytest-sugar]]
+
+[pytest-sugar](https://github.com/Frozenball/pytest-sugar)는 테스트가 보여지는 형태를 개선하고,
+진행 상황 바를 추가하며, 실패한 테스트와 검증을 즉시 표시하는 플러그인입니다. 설치하면 자동으로 활성화됩니다.
+
+```bash
+pip install pytest-sugar
+```
+
+pytest-sugar 없이 테스트를 실행하려면 다음과 같습니다:
+
+```bash
+pytest -p no:sugar
+```
+
+또는 제거하세요.
+
+
+
+#### 각 하위 테스트 이름과 진행 상황 보고[[report-each-sub-test-name-and-its-progress]]
+
+`pytest`를 통해 단일 또는 그룹의 테스트를 실행하는 경우(`pip install pytest-pspec` 이후):
+
+```bash
+pytest --pspec tests/test_optimization.py
+```
+
+#### 실패한 테스트 즉시 표시[[instantly-shows-failed-tests]]
+
+[pytest-instafail](https://github.com/pytest-dev/pytest-instafail)은 테스트 세션의 끝까지 기다리지 않고
+실패 및 오류를 즉시 표시합니다.
+
+```bash
+pip install pytest-instafail
+```
+
+```bash
+pytest --instafail
+```
+
+### GPU 사용 여부[[to-GPU-or-not-to-GPU]]
+
+GPU가 활성화된 환경에서, CPU 전용 모드로 테스트하려면 `CUDA_VISIBLE_DEVICES=""`를 추가합니다:
+
+```bash
+CUDA_VISIBLE_DEVICES="" pytest tests/utils/test_logging.py
+```
+
+또는 다중 GPU가 있는 경우 `pytest`에서 사용할 GPU를 지정할 수도 있습니다.
+예를 들어, GPU `0` 및 `1`이 있는 경우 다음을 실행할 수 있습니다:
+
+```bash
+CUDA_VISIBLE_DEVICES="1" pytest tests/utils/test_logging.py
+```
+
+이렇게 하면 다른 GPU에서 다른 작업을 실행하려는 경우 유용합니다.
+
+일부 테스트는 반드시 CPU 전용으로 실행해야 하며, 일부는 CPU 또는 GPU 또는 TPU에서 실행해야 하고, 일부는 여러 GPU에서 실행해야 합니다.
+다음 스킵 데코레이터는 테스트의 요구 사항을 CPU/GPU/TPU별로 설정하는 데 사용됩니다:
+
+- `require_torch` - 이 테스트는 torch에서만 실행됩니다.
+- `require_torch_gpu` - `require_torch`에 추가로 적어도 1개의 GPU가 필요합니다.
+- `require_torch_multi_gpu` - `require_torch`에 추가로 적어도 2개의 GPU가 필요합니다.
+- `require_torch_non_multi_gpu` - `require_torch`에 추가로 0개 또는 1개의 GPU가 필요합니다.
+- `require_torch_up_to_2_gpus` - `require_torch`에 추가로 0개, 1개 또는 2개의 GPU가 필요합니다.
+- `require_torch_xla` - `require_torch`에 추가로 적어도 1개의 TPU가 필요합니다.
+
+GPU 요구 사항을 표로 정리하면 아래와 같습니디ㅏ:
+
+
+| n gpus | decorator |
+|--------+--------------------------------|
+| `>= 0` | `@require_torch` |
+| `>= 1` | `@require_torch_gpu` |
+| `>= 2` | `@require_torch_multi_gpu` |
+| `< 2` | `@require_torch_non_multi_gpu` |
+| `< 3` | `@require_torch_up_to_2_gpus` |
+
+
+예를 들어, 2개 이상의 GPU가 있고 pytorch가 설치되어 있을 때에만 실행되어야 하는 테스트는 다음과 같습니다:
+
+```python no-style
+@require_torch_multi_gpu
+def test_example_with_multi_gpu():
+```
+
+`tensorflow`가 필요한 경우 `require_tf` 데코레이터를 사용합니다. 예를 들어 다음과 같습니다:
+
+```python no-style
+@require_tf
+def test_tf_thing_with_tensorflow():
+```
+
+이러한 데코레이터는 중첩될 수 있습니다.
+예를 들어, 느린 테스트로 진행되고 pytorch에서 적어도 하나의 GPU가 필요한 경우 다음과 같이 설정할 수 있습니다:
+
+```python no-style
+@require_torch_gpu
+@slow
+def test_example_slow_on_gpu():
+```
+
+`@parametrized`와 같은 일부 데코레이터는 테스트 이름을 다시 작성하기 때문에 `@require_*` 스킵 데코레이터는 올바르게 작동하려면 항상 맨 마지막에 나열되어야 합니다.
+다음은 올바른 사용 예입니다:
+
+```python no-style
+@parameterized.expand(...)
+@require_torch_multi_gpu
+def test_integration_foo():
+```
+
+`@pytest.mark.parametrize`에는 이러한 순서 문제는 없으므로 처음 혹은 마지막에 위치시킬 수 있고 이러한 경우에도 잘 작동할 것입니다.
+하지만 unittest가 아닌 경우에만 작동합니다.
+
+테스트 내부에서 다음을 사용할 수 있습니다:
+
+- 사용 가능한 GPU 수:
+
+```python
+from transformers.testing_utils import get_gpu_count
+
+n_gpu = get_gpu_count() #torch와 tf와 함께 작동
+```
+
+### 분산 훈련[[distributed-training]]
+
+`pytest`는 분산 훈련을 직접적으로 다루지 못합니다.
+이를 시도하면 하위 프로세스가 올바른 작업을 수행하지 않고 `pytest`라고 생각하기에 테스트 스위트를 반복해서 실행하게 됩니다.
+그러나 일반 프로세스를 생성한 다음 여러 워커를 생성하고 IO 파이프를 관리하도록 하면 동작합니다.
+
+다음은 사용 가능한 테스트입니다:
+
+- [test_trainer_distributed.py](https://github.com/huggingface/transformers/tree/main/tests/trainer/test_trainer_distributed.py)
+- [test_deepspeed.py](https://github.com/huggingface/transformers/tree/main/tests/deepspeed/test_deepspeed.py)
+
+실행 지점으로 바로 이동하려면, 해당 테스트에서 `execute_subprocess_async` 호출을 검색하세요.
+
+이러한 테스트를 실행하려면 적어도 2개의 GPU가 필요합니다.
+
+```bash
+CUDA_VISIBLE_DEVICES=0,1 RUN_SLOW=1 pytest -sv tests/test_trainer_distributed.py
+```
+
+### 출력 캡처[[output-capture]]
+
+테스트 실행 중 `stdout` 및 `stderr`로 전송된 모든 출력이 캡처됩니다.
+테스트나 설정 메소드가 실패하면 캡처된 출력은 일반적으로 실패 추적 정보와 함께 표시됩니다.
+
+출력 캡처를 비활성화하고 `stdout` 및 `stderr`를 정상적으로 받으려면 `-s` 또는 `--capture=no`를 사용하세요:
+
+```bash
+pytest -s tests/utils/test_logging.py
+```
+
+테스트 결과를 JUnit 형식의 출력으로 보내려면 다음을 사용하세요:
+
+```bash
+py.test tests --junitxml=result.xml
+```
+
+### 색상 조절[[color-control]]
+
+색상이 없게 하려면 다음과 같이 설정하세요(예를 들어 흰색 배경에 노란색 글씨는 가독성이 좋지 않습니다):
+
+```bash
+pytest --color=no tests/utils/test_logging.py
+```
+
+### online pastebin service에 테스트 보고서 전송[[sending test report to online pastebin service]]
+
+각 테스트 실패에 대한 URL을 만듭니다:
+
+```bash
+pytest --pastebin=failed tests/utils/test_logging.py
+```
+
+이렇게 하면 각 실패에 대한 URL을 제공하는 remote Paste service에 테스트 실행 정보를 제출합니다.
+일반적인 테스트를 선택할 수도 있고 혹은 특정 실패만 보내려면 `-x`와 같이 추가할 수도 있습니다.
+
+전체 테스트 세션 로그에 대한 URL을 생성합니다:
+
+```bash
+pytest --pastebin=all tests/utils/test_logging.py
+```
+
+## 테스트 작성[[writing-tests]]
+
+🤗 transformers 테스트는 대부분 `unittest`를 기반으로 하지만,
+`pytest`에서 실행되므로 대부분의 경우 두 시스템의 기능을 사용할 수 있습니다.
+
+지원되는 기능에 대해 [여기](https://docs.pytest.org/en/stable/unittest.html)에서 확인할 수 있지만,
+기억해야 할 중요한 점은 대부분의 `pytest` fixture가 작동하지 않는다는 것입니다.
+파라미터화도 작동하지 않지만, 우리는 비슷한 방식으로 작동하는 `parameterized` 모듈을 사용합니다.
+
+
+### 매개변수화[[parametrization]]
+
+동일한 테스트를 다른 인수로 여러 번 실행해야 하는 경우가 종종 있습니다.
+테스트 내에서 이 작업을 수행할 수 있지만, 그렇게 하면 하나의 인수 세트에 대해 테스트를 실행할 수 없습니다.
+
+```python
+# test_this1.py
+import unittest
+from parameterized import parameterized
+
+
+class TestMathUnitTest(unittest.TestCase):
+ @parameterized.expand(
+ [
+ ("negative", -1.5, -2.0),
+ ("integer", 1, 1.0),
+ ("large fraction", 1.6, 1),
+ ]
+ )
+ def test_floor(self, name, input, expected):
+ assert_equal(math.floor(input), expected)
+```
+
+이제 기본적으로 이 테스트는 `test_floor`의 마지막 3개 인수가
+매개변수 목록의 해당 인수에 할당되는 것으로 3번 실행될 것입니다.
+
+그리고 `negative` 및 `integer` 매개변수 집합만 실행하려면 다음과 같이 실행할 수 있습니다:
+
+```bash
+pytest -k "negative and integer" tests/test_mytest.py
+```
+
+또는 `negative` 하위 테스트를 제외한 모든 서브 테스트를 다음과 같이 실행할 수 있습니다:
+
+```bash
+pytest -k "not negative" tests/test_mytest.py
+```
+
+앞에서 언급한 `-k` 필터를 사용하는 것 외에도,
+각 서브 테스트의 정확한 이름을 확인한 후에 일부 혹은 전체 서브 테스트를 실행할 수 있습니다.
+
+```bash
+pytest test_this1.py --collect-only -q
+```
+
+그리고 다음의 내용을 확인할 수 있을 것입니다:
+
+```bash
+test_this1.py::TestMathUnitTest::test_floor_0_negative
+test_this1.py::TestMathUnitTest::test_floor_1_integer
+test_this1.py::TestMathUnitTest::test_floor_2_large_fraction
+```
+
+2개의 특정한 서브 테스트만 실행할 수도 있습니다:
+
+```bash
+pytest test_this1.py::TestMathUnitTest::test_floor_0_negative test_this1.py::TestMathUnitTest::test_floor_1_integer
+```
+
+`transformers`의 개발자 종속성에 이미 있는 [parameterized](https://pypi.org/project/parameterized/) 모듈은
+`unittests`와 `pytest` 테스트 모두에서 작동합니다.
+
+그러나 테스트가 `unittest`가 아닌 경우 `pytest.mark.parametrize`를 사용할 수 있습니다(이미 있는 일부 테스트에서 사용되는 경우도 있습니다.
+주로 `examples` 하위에 있습니다).
+
+다음은 `pytest`의 `parametrize` 마커를 사용한 동일한 예입니다:
+
+```python
+# test_this2.py
+import pytest
+
+
+@pytest.mark.parametrize(
+ "name, input, expected",
+ [
+ ("negative", -1.5, -2.0),
+ ("integer", 1, 1.0),
+ ("large fraction", 1.6, 1),
+ ],
+)
+def test_floor(name, input, expected):
+ assert_equal(math.floor(input), expected)
+```
+
+`parameterized`와 마찬가지로 `pytest.mark.parametrize`를 사용하면
+`-k` 필터가 작동하지 않는 경우에도 실행할 서브 테스트를 정확하게 지정할 수 있습니다.
+단, 이 매개변수화 함수는 서브 테스트의 이름 집합을 약간 다르게 생성합니다. 다음과 같은 모습입니다:
+
+```bash
+pytest test_this2.py --collect-only -q
+```
+
+그리고 다음의 내용을 확인할 수 있을 것입니다:
+
+```bash
+test_this2.py::test_floor[integer-1-1.0]
+test_this2.py::test_floor[negative--1.5--2.0]
+test_this2.py::test_floor[large fraction-1.6-1]
+```
+
+특정한 테스트에 대해서만 실행할 수도 있습니다:
+
+```bash
+pytest test_this2.py::test_floor[negative--1.5--2.0] test_this2.py::test_floor[integer-1-1.0]
+```
+
+이전의 예시와 같이 실행할 수 있습니다.
+
+
+
+### 파일 및 디렉터리[[files-and-directories]]
+
+테스트에서 종종 현재 테스트 파일과 관련된 상대적인 위치를 알아야 하는 경우가 있습니다.
+테스트가 여러 디렉터리에서 호출되거나 깊이가 다른 하위 디렉터리에 있을 수 있기 때문에 그 위치를 아는 것은 간단하지 않습니다.
+`transformers.test_utils.TestCasePlus`라는 헬퍼 클래스는 모든 기본 경로를 처리하고 간단한 액세서를 제공하여 이 문제를 해결합니다:
+
+
+- `pathlib` 객체(완전히 정해진 경로)
+
+ - `test_file_path` - 현재 테스트 파일 경로 (예: `__file__`)
+ - test_file_dir` - 현재 테스트 파일이 포함된 디렉터리
+ - tests_dir` - `tests` 테스트 스위트의 디렉터리
+ - examples_dir` - `examples` 테스트 스위트의 디렉터리
+ - repo_root_dir` - 저장소 디렉터리
+ - src_dir` - `src`의 디렉터리(예: `transformers` 하위 디렉터리가 있는 곳)
+
+- 문자열로 변환된 경로---위와 동일하지만, `pathlib` 객체가 아닌 문자열로 경로를 반환합니다:
+
+ - `test_file_path_str`
+ - `test_file_dir_str`
+ - `tests_dir_str`
+ - `examples_dir_str`
+ - `repo_root_dir_str`
+ - `src_dir_str`
+
+위의 내용을 사용하려면 테스트가 'transformers.test_utils.TestCasePlus'의 서브클래스에 있는지 확인해야 합니다.
+예를 들어 다음과 같습니다:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class PathExampleTest(TestCasePlus):
+ def test_something_involving_local_locations(self):
+ data_dir = self.tests_dir / "fixtures/tests_samples/wmt_en_ro"
+```
+
+만약 `pathlib`를 통해 경로를 조작할 필요가 없거나 경로를 문자열로만 필요로 하는 경우에는 `pathlib` 객체에 `str()`을 호출하거나 `_str`로 끝나는 접근자를 사용할 수 있습니다.
+예를 들어 다음과 같습니다:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class PathExampleTest(TestCasePlus):
+ def test_something_involving_stringified_locations(self):
+ examples_dir = self.examples_dir_str
+```
+
+### 임시 파일 및 디렉터리[[temporary-files-and-directories]]
+
+고유한 임시 파일 및 디렉터리를 사용하는 것은 병렬 테스트 실행에 있어 필수적입니다.
+이렇게 함으로써 테스트들이 서로의 데이터를 덮어쓰지 않게 할 수 있습니다. 또한 우리는 생성된 테스트의 종료 단계에서 이러한 임시 파일 및 디렉터리를 제거하고 싶습니다.
+따라서 이러한 요구 사항을 충족시켜주는 `tempfile`과 같은 패키지를 사용하는 것이 중요합니다.
+
+그러나 테스트를 디버깅할 때는 임시 파일이나 디렉터리에 들어가는 내용을 확인할 수 있어야 하며,
+재실행되는 각 테스트마다 임시 파일이나 디렉터리의 경로에 대해 무작위 값이 아닌 정확한 값을 알고 싶을 것입니다.
+
+`transformers.test_utils.TestCasePlus`라는 도우미 클래스는 이러한 목적에 가장 적합합니다.
+이 클래스는 `unittest.TestCase`의 하위 클래스이므로, 우리는 이것을 테스트 모듈에서 쉽게 상속할 수 있습니다.
+
+다음은 해당 클래스를 사용하는 예시입니다:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class ExamplesTests(TestCasePlus):
+ def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+```
+
+이 코드는 고유한 임시 디렉터리를 생성하고 `tmp_dir`을 해당 위치로 설정합니다.
+
+- 고유한 임시 디렉터리를 생성합니다:
+
+```python
+def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir()
+```
+
+`tmp_dir`에는 생성된 임시 디렉터리의 경로가 포함됩니다.
+이는 테스트의 종료 단계에서 자동으로 제거됩니다.
+
+- 선택한 경로로 임시 디렉터리 생성 후에 테스트 시작 전에 비어 있는 상태인지 확인하고, 테스트 후에는 비우지 마세요.
+
+```python
+def test_whatever(self):
+ tmp_dir = self.get_auto_remove_tmp_dir("./xxx")
+```
+
+이것은 디버깅할 때 특정 디렉터리를 모니터링하고,
+그 디렉터리에 이전에 실행된 테스트가 데이터를 남기지 않도록 하는 데에 유용합니다.
+
+- `before` 및 `after` 인수를 직접 오버라이딩하여 기본 동작을 변경할 수 있으며
+다음 중 하나의 동작으로 이어집니다:
+
+ - `before=True`: 테스트 시작 시 임시 디렉터리가 항상 지워집니다.
+ - `before=False`: 임시 디렉터리가 이미 존재하는 경우 기존 파일은 그대로 남습니다.
+ - `after=True`: 테스트 종료 시 임시 디렉터리가 항상 삭제됩니다.
+ - `after=False`: 테스트 종료 시 임시 디렉터리가 항상 그대로 유지됩니다.
+
+
+
+`rm -r`에 해당하는 명령을 안전하게 실행하기 위해,
+명시적인 `tmp_dir`을 사용하는 경우 프로젝트 저장소 체크 아웃의 하위 디렉터리만 허용됩니다.
+따라서 실수로 `/tmp`가 아닌 중요한 파일 시스템의 일부가 삭제되지 않도록 항상 `./`로 시작하는 경로를 전달해야 합니다.
+
+
+
+
+
+각 테스트는 여러 개의 임시 디렉터리를 등록할 수 있으며,
+별도로 요청하지 않는 한 모두 자동으로 제거됩니다.
+
+
+
+### 임시 sys.path 오버라이드[[temporary-sys.path-override]]
+
+`sys.path`를 다른 테스트로 임시로 오버라이드하기 위해 예를 들어 `ExtendSysPath` 컨텍스트 관리자를 사용할 수 있습니다.
+예를 들어 다음과 같습니다:
+
+
+```python
+import os
+from transformers.testing_utils import ExtendSysPath
+
+bindir = os.path.abspath(os.path.dirname(__file__))
+with ExtendSysPath(f"{bindir}/.."):
+ from test_trainer import TrainerIntegrationCommon # noqa
+```
+
+### 테스트 건너뛰기[[skipping-tests]]
+
+이것은 버그가 발견되어 새로운 테스트가 작성되었지만 아직 그 버그가 수정되지 않은 경우에 유용합니다.
+이 테스트를 주 저장소에 커밋하려면 `make test` 중에 건너뛰도록 해야 합니다.
+
+방법:
+
+- **skip**은 테스트가 일부 조건이 충족될 경우에만 통과될 것으로 예상되고, 그렇지 않으면 pytest가 전체 테스트를 건너뛰어야 함을 의미합니다.
+일반적인 예로는 Windows가 아닌 플랫폼에서 Windows 전용 테스트를 건너뛰거나
+외부 리소스(예를 들어 데이터베이스)에 의존하는 테스트를 건너뛰는 것이 있습니다.
+
+- **xfail**은 테스트가 특정한 이유로 인해 실패할 것으로 예상하는 것을 의미합니다.
+일반적인 예로는 아직 구현되지 않은 기능이나 아직 수정되지 않은 버그의 테스트가 있습니다.
+`xfail`로 표시된 테스트가 예상대로 실패하지 않고 통과된 경우, 이것은 xpass이며 테스트 결과 요약에 기록됩니다.
+
+두 가지 중요한 차이점 중 하나는 `skip`은 테스트를 실행하지 않지만 `xfail`은 실행한다는 것입니다.
+따라서 오류가 있는 코드가 일부 테스트에 영향을 미칠 수 있는 경우 `xfail`을 사용하지 마세요.
+
+#### 구현[[implementation]]
+
+- 전체 테스트를 무조건 건너뛰려면 다음과 같이 할 수 있습니다:
+
+```python no-style
+@unittest.skip(reason="this bug needs to be fixed")
+def test_feature_x():
+```
+
+또는 pytest를 통해:
+
+```python no-style
+@pytest.mark.skip(reason="this bug needs to be fixed")
+```
+
+또는 `xfail` 방식으로:
+
+```python no-style
+@pytest.mark.xfail
+def test_feature_x():
+```
+
+- 테스트 내부에서 내부 확인에 따라 테스트를 건너뛰는 방법은 다음과 같습니다:
+
+```python
+def test_feature_x():
+ if not has_something():
+ pytest.skip("unsupported configuration")
+```
+
+또는 모듈 전체:
+
+```python
+import pytest
+
+if not pytest.config.getoption("--custom-flag"):
+ pytest.skip("--custom-flag is missing, skipping tests", allow_module_level=True)
+```
+
+또는 `xfail` 방식으로:
+
+```python
+def test_feature_x():
+ pytest.xfail("expected to fail until bug XYZ is fixed")
+```
+
+- import가 missing된 모듈이 있을 때 그 모듈의 모든 테스트를 건너뛰는 방법:
+
+```python
+docutils = pytest.importorskip("docutils", minversion="0.3")
+```
+
+- 조건에 따라 테스트를 건너뛰는 방법:
+
+```python no-style
+@pytest.mark.skipif(sys.version_info < (3,6), reason="requires python3.6 or higher")
+def test_feature_x():
+```
+
+또는:
+
+```python no-style
+@unittest.skipIf(torch_device == "cpu", "Can't do half precision")
+def test_feature_x():
+```
+
+또는 모듈 전체를 건너뛰는 방법:
+
+```python no-style
+@pytest.mark.skipif(sys.platform == 'win32', reason="does not run on windows")
+class TestClass():
+ def test_feature_x(self):
+```
+
+보다 자세한 예제 및 방법은 [여기](https://docs.pytest.org/en/latest/skipping.html)에서 확인할 수 있습니다.
+
+### 느린 테스트[[slow-tests]]
+
+테스트 라이브러리는 지속적으로 확장되고 있으며, 일부 테스트는 실행하는 데 몇 분이 걸립니다.
+그리고 우리에게는 테스트 스위트가 CI를 통해 완료되기까지 한 시간을 기다릴 여유가 없습니다.
+따라서 필수 테스트를 위한 일부 예외를 제외하고 느린 테스트는 다음과 같이 표시해야 합니다.
+
+```python no-style
+from transformers.testing_utils import slow
+@slow
+def test_integration_foo():
+```
+
+`@slow`로 표시된 테스트를 실행하려면 `RUN_SLOW=1` 환경 변수를 설정하세요. 예를 들어 다음과 같습니다:
+
+```bash
+RUN_SLOW=1 pytest tests
+```
+
+`@parameterized`와 같은 몇 가지 데코레이터는 테스트 이름을 다시 작성합니다.
+그러므로 `@slow`와 나머지 건너뛰기 데코레이터 `@require_*`가 올바르게 작동되려면 마지막에 나열되어야 합니다. 다음은 올바른 사용 예입니다.
+
+```python no-style
+@parameterized.expand(...)
+@slow
+def test_integration_foo():
+```
+
+이 문서의 초반부에 설명된 것처럼 느린 테스트는 PR의 CI 확인이 아닌 예약된 일정 기반으로 실행됩니다.
+따라서 PR 제출 중에 일부 문제를 놓친 채로 병합될 수 있습니다.
+이러한 문제들은 다음번의 예정된 CI 작업 중에 감지됩니다.
+하지만 PR을 제출하기 전에 자신의 컴퓨터에서 느린 테스트를 실행하는 것 또한 중요합니다.
+
+느린 테스트로 표시해야 하는지 여부를 결정하는 대략적인 결정 기준은 다음과 같습니다.
+
+만약 테스트가 라이브러리의 내부 구성 요소 중 하나에 집중되어 있다면(예: 모델링 파일, 토큰화 파일, 파이프라인),
+해당 테스트를 느린 테스트 스위트에서 실행해야 합니다.
+만약 라이브러리의 다른 측면(예: 문서 또는 예제)에 집중되어 있다면,
+해당 테스트를 느린 테스트 스위트에서 실행해야 합니다. 그리고 이 접근 방식을 보완하기 위해 예외를 만들어야 합니다.
+
+- 무거운 가중치 세트나 50MB보다 큰 데이터셋을 다운로드해야 하는 모든 테스트(예: 모델 통합 테스트, 토크나이저 통합 테스트, 파이프라인 통합 테스트)를
+ 느린 테스트로 설정해야 합니다.
+ 새로운 모델을 추가하는 경우 통합 테스트용으로 무작위 가중치로 작은 버전을 만들어 허브에 업로드해야 합니다.
+ 이 내용은 아래 단락에서 설명됩니다.
+- 특별히 빠르게 실행되도록 최적화되지 않은 학습을 수행해야 하는 테스트는 느린 테스트로 설정해야 합니다.
+- 느리지 않아야 할 테스트 중 일부가 극도로 느린 경우
+ 예외를 도입하고 이를 `@slow`로 설정할 수 있습니다.
+ 대용량 파일을 디스크에 저장하고 불러오는 자동 모델링 테스트는 `@slow`으로 표시된 테스트의 좋은 예입니다.
+- CI에서 1초 이내에 테스트가 완료되는 경우(다운로드 포함)에는 느린 테스트가 아니어야 합니다.
+
+느린 테스트가 아닌 경우에는 다양한 내부를 완전히 커버하면서 빠르게 유지되어야 합니다.
+예를 들어, 무작위 가중치를 사용하여 특별히 생성된 작은 모델로 테스트하면 상당한 커버리지를 얻을 수 있습니다.
+이러한 모델은 최소한의 레이어 수(예: 2), 어휘 크기(예: 1000) 등의 요소만 가집니다. 그런 다음 `@slow` 테스트는 대형 느린 모델을 사용하여 정성적인 테스트를 수행할 수 있습니다.
+이러한 작은 모델을 사용하는 방법을 확인하려면 다음과 같이 *tiny* 모델을 찾아보세요.
+
+```bash
+grep tiny tests examples
+```
+
+다음은 작은 모델[stas/tiny-wmt19-en-de](https://huggingface.co/stas/tiny-wmt19-en-de)을 만든
+[script](https://github.com/huggingface/transformers/tree/main/scripts/fsmt/fsmt-make-tiny-model.py) 예시입니다.
+특정 모델의 아키텍처에 맞게 쉽게 조정할 수 있습니다.
+
+예를 들어 대용량 모델을 다운로드하는 경우 런타임을 잘못 측정하기 쉽지만,
+로컬에서 테스트하면 다운로드한 파일이 캐시되어 다운로드 시간이 측정되지 않습니다.
+대신 CI 로그의 실행 속도 보고서를 확인하세요(`pytest --durations=0 tests`의 출력).
+
+이 보고서는 느린 이상값으로 표시되지 않거나 빠르게 다시 작성해야 하는 느린 이상값을 찾는 데도 유용합니다.
+CI에서 테스트 스위트가 느려지기 시작하면 이 보고서의 맨 위 목록에 가장 느린 테스트가 표시됩니다.
+
+
+
+### stdout/stderr 출력 테스트[[testing-the-stdout/stderr-output]]
+
+`stdout` 및/또는 `stderr`로 쓰는 함수를 테스트하려면 `pytest`의 [capsys 시스템](https://docs.pytest.org/en/latest/capture.html)을 사용하여 해당 스트림에 액세스할 수 있습니다.
+다음과 같이 수행할 수 있습니다.
+
+```python
+import sys
+
+
+def print_to_stdout(s):
+ print(s)
+
+
+def print_to_stderr(s):
+ sys.stderr.write(s)
+
+
+def test_result_and_stdout(capsys):
+ msg = "Hello"
+ print_to_stdout(msg)
+ print_to_stderr(msg)
+ out, err = capsys.readouterr() # 캡처된 출력 스트림 사용
+ # 선택 사항: 캡처된 스트림 재생성
+ sys.stdout.write(out)
+ sys.stderr.write(err)
+ # 테스트:
+ assert msg in out
+ assert msg in err
+```
+
+그리고, 물론 대부분의 경우에는 `stderr`는 예외의 일부로 제공됩니다.
+그러므로 해당 경우에는 try/except를 사용해야 합니다.
+
+```python
+def raise_exception(msg):
+ raise ValueError(msg)
+
+
+def test_something_exception():
+ msg = "Not a good value"
+ error = ""
+ try:
+ raise_exception(msg)
+ except Exception as e:
+ error = str(e)
+ assert msg in error, f"{msg} is in the exception:\n{error}"
+```
+
+`stdout`를 캡처하는 또 다른 방법은 `contextlib.redirect_stdout`를 사용하는 것입니다.
+
+```python
+from io import StringIO
+from contextlib import redirect_stdout
+
+
+def print_to_stdout(s):
+ print(s)
+
+
+def test_result_and_stdout():
+ msg = "Hello"
+ buffer = StringIO()
+ with redirect_stdout(buffer):
+ print_to_stdout(msg)
+ out = buffer.getvalue()
+ # 선택 사항: 캡처된 스트림 재생성
+ sys.stdout.write(out)
+ # 테스트:
+ assert msg in out
+```
+
+`stdout` 캡처에 관련된 중요한 문제 중 하나는 보통 `print`에서 이전에 인쇄된 내용을 재설정하는 `\r` 문자가 포함될 수 있다는 것입니다.
+`pytest`에서는 문제가 없지만 `pytest -s`에서는 이러한 문자가 버퍼에 포함되므로
+`-s`가 있거나 없는 상태에서 태스트를 수행할 수 있으려면 캡처된 출력에 대해 추가적인 정리가 필요합니다.
+이 경우에는 `re.sub(r'~.*\r', '', buf, 0, re.M)`을 사용할 수 있습니다.
+
+하지만 도우미 컨텍스트 관리자 래퍼를 사용하면
+출력에 `\r`이 포함되어 있는지의 여부에 관계없이 모든 것을 자동으로 처리하므로 편리합니다.
+
+```python
+from transformers.testing_utils import CaptureStdout
+
+with CaptureStdout() as cs:
+ function_that_writes_to_stdout()
+print(cs.out)
+```
+
+다음은 전체 테스트 예제입니다.
+
+```python
+from transformers.testing_utils import CaptureStdout
+
+msg = "Secret message\r"
+final = "Hello World"
+with CaptureStdout() as cs:
+ print(msg + final)
+assert cs.out == final + "\n", f"captured: {cs.out}, expecting {final}"
+```
+
+`stderr`를 캡처하고 싶다면, 대신 `CaptureStderr` 클래스를 사용하세요.
+
+```python
+from transformers.testing_utils import CaptureStderr
+
+with CaptureStderr() as cs:
+ function_that_writes_to_stderr()
+print(cs.err)
+```
+
+두 스트림을 동시에 캡처해야 한다면, 부모 `CaptureStd` 클래스를 사용하세요.
+
+```python
+from transformers.testing_utils import CaptureStd
+
+with CaptureStd() as cs:
+ function_that_writes_to_stdout_and_stderr()
+print(cs.err, cs.out)
+```
+
+또한, 테스트의 디버깅을 지원하기 위해
+이러한 컨텍스트 관리자는 기본적으로 컨텍스트에서 종료할 때 캡처된 스트림을 자동으로 다시 실행합니다.
+
+
+### 로거 스트림 캡처[[capturing-logger-stream]]
+
+로거 출력을 검증해야 하는 경우 `CaptureLogger`를 사용할 수 있습니다.
+
+```python
+from transformers import logging
+from transformers.testing_utils import CaptureLogger
+
+msg = "Testing 1, 2, 3"
+logging.set_verbosity_info()
+logger = logging.get_logger("transformers.models.bart.tokenization_bart")
+with CaptureLogger(logger) as cl:
+ logger.info(msg)
+assert cl.out, msg + "\n"
+```
+
+### 환경 변수를 이용하여 테스트[[testing-with-environment-variables]]
+
+특정 테스트의 환경 변수 영향을 검증하려면
+`transformers.testing_utils.mockenv`라는 도우미 데코레이터를 사용할 수 있습니다.
+
+```python
+from transformers.testing_utils import mockenv
+
+
+class HfArgumentParserTest(unittest.TestCase):
+ @mockenv(TRANSFORMERS_VERBOSITY="error")
+ def test_env_override(self):
+ env_level_str = os.getenv("TRANSFORMERS_VERBOSITY", None)
+```
+
+일부 경우에는 외부 프로그램을 호출해야할 수도 있는데, 이 때에는 여러 개의 로컬 경로를 포함하는 `os.environ`에서 `PYTHONPATH`의 설정이 필요합니다.
+헬퍼 클래스 `transformers.test_utils.TestCasePlus`가 도움이 됩니다:
+
+```python
+from transformers.testing_utils import TestCasePlus
+
+
+class EnvExampleTest(TestCasePlus):
+ def test_external_prog(self):
+ env = self.get_env()
+ # 이제 `env`를 사용하여 외부 프로그램 호출
+```
+
+테스트 파일이 `tests` 테스트 스위트 또는 `examples`에 있는지에 따라
+`env[PYTHONPATH]`가 두 디렉터리 중 하나를 포함하도록 설정되며,
+현재 저장소에 대해 테스트가 수행되도록 `src` 디렉터리도 포함됩니다.
+테스트 호출 이전에 설정된 경우에는 `env[PYTHONPATH]`를 그대로 사용합니다.
+
+이 헬퍼 메소드는 `os.environ` 객체의 사본을 생성하므로 원본은 그대로 유지됩니다.
+
+
+### 재현 가능한 결과 얻기[[getting-reproducible-results]]
+
+일부 상황에서 테스트에서 임의성을 제거하여 동일하게 재현 가능한 결과를 얻고 싶을 수 있습니다.
+이를 위해서는 다음과 같이 시드를 고정해야 합니다.
+
+```python
+seed = 42
+
+# 파이썬 RNG
+import random
+
+random.seed(seed)
+
+# 파이토치 RNG
+import torch
+
+torch.manual_seed(seed)
+torch.backends.cudnn.deterministic = True
+if torch.cuda.is_available():
+ torch.cuda.manual_seed_all(seed)
+
+# 넘파이 RNG
+import numpy as np
+
+np.random.seed(seed)
+
+# 텐서플로 RNG
+tf.random.set_seed(seed)
+```
+
+### 테스트 디버깅[[debugging tests]]
+
+경고가 있는 곳에서 디버거를 시작하려면 다음을 수행하세요.
+
+```bash
+pytest tests/utils/test_logging.py -W error::UserWarning --pdb
+```
+
+## Github Actions 워크플로우 작업 처리[[working-with-github-actions-workflows]]
+
+셀프 푸시 워크플로우 CI 작업을 트리거하려면, 다음을 수행해야 합니다.
+
+1. `transformers` 원본에서 새 브랜치를 만듭니다(포크가 아닙니다!).
+2. 브랜치 이름은 `ci_` 또는 `ci-`로 시작해야 합니다(`main`도 트리거하지만 `main`에서는 PR을 할 수 없습니다).
+ 또한 특정 경로에 대해서만 트리거되므로 이 문서가 작성된 후에 변경된 내용은
+ [여기](https://github.com/huggingface/transformers/blob/main/.github/workflows/self-push.yml)의 *push:*에서 확인할 수 있습니다.
+3. 이 브랜치에서 PR을 생성합니다
+4. 그런 다음 [여기](https://github.com/huggingface/transformers/actions/workflows/self-push.yml)에서 작업이 나타나는지 확인할 수 있습니다.
+ 백로그가 있는 경우, 바로 실행되지 않을 수도 있습니다.
+
+
+
+
+## 실험적인 CI 기능 테스트[[testing-Experimental-CI-Features]]
+
+CI 기능을 테스트하는 것은 일반 CI 작동에 방해가 될 수 있기 때문에 잠재적으로 문제가 발생할 수 있습니다.
+따라서 새로운 CI 기능을 추가하는 경우 다음과 같이 수행해야 합니다.
+
+1. 테스트해야 할 내용을 테스트하는 새로운 전용 작업을 생성합니다.
+2. 새로운 작업은 항상 성공해야만 녹색 ✓를 받을 수 있습니다(아래에 자세한 내용이 있습니다).
+3. 다양한 PR 유형에 대한 확인을 위해
+ (사용자 포크 브랜치, 포크되지 않은 브랜치, github.com UI 직접 파일 편집에서 생성된 브랜치, 강제 푸시 등 PR의 유형은 아주 다양합니다.)
+ 며칠 동안 실험 작업의 로그를 모니터링하면서 실행해봅니다.
+ (의도적으로 항상 녹색을 표시하므로 작업 전체가 녹색은 아니라는 점에 유의합니다.)
+4. 모든 것이 안정적인지 확인한 후, 새로운 변경 사항을 기존 작업에 병합합니다.
+
+이렇게 하면 CI 기능 자체에 대한 실험이 일반 작업 흐름에 방해가 되지 않습니다.
+
+그러나 새로운 CI 기능이 개발 중인 동안, 항상 성공하도록 할 수 있는 방법은 무엇일까요?
+
+TravisCI와 같은 일부 CI는 `ignore-step-failure`를 지원하며 전체 작업을 성공한 것으로 보고하지만,
+현재 우리가 사용하는 CircleCI와 Github Actions는 이를 지원하지 않습니다.
+
+따라서 다음과 같은 해결책을 사용할 수 있습니다.
+
+1. bash 스크립트에서 가능한 많은 오류를 억제하기 위해 실행 명령의 시작 부분에 `set +euo pipefail`을 추가합니다.
+2. 마지막 명령은 반드시 성공해야 합니다. `echo "done"` 또는 `true`를 사용하면 됩니다.
+
+예시는 다음과 같습니다.
+
+```yaml
+- run:
+ name: run CI experiment
+ command: |
+ set +euo pipefail
+ echo "setting run-all-despite-any-errors-mode"
+ this_command_will_fail
+ echo "but bash continues to run"
+ # emulate another failure
+ false
+ # but the last command must be a success
+ echo "during experiment do not remove: reporting success to CI, even if there were failures"
+```
+
+간단한 명령의 경우 다음과 같이 수행할 수도 있습니다.
+
+```bash
+cmd_that_may_fail || true
+```
+
+결과에 만족한 후에는 물론, 실험적인 단계 또는 작업을 일반 작업의 나머지 부분과 통합하면서
+`set +euo pipefail` 또는 기타 추가한 요소를 제거하여
+실험 작업이 일반 CI 작동에 방해되지 않도록 해야 합니다.
+
+이 전반적인 과정은 실험 단계가 PR의 전반적인 상태에 영향을 주지 않고 실패하도록
+`allow-failure`와 같은 기능을 설정할 수 있다면 훨씬 더 쉬웠을 것입니다.
+그러나 앞에서 언급한 바와 같이 CircleCI와 Github Actions는 현재 이러한 기능들 지원하지 않습니다.
+
+이 기능의 지원을 위한 투표에 참여하고 CI 관련 스레드들에서 이러한 상황을 확인할 수도 있습니다.
+
+- [Github Actions:](https://github.com/actions/toolkit/issues/399)
+- [CircleCI:](https://ideas.circleci.com/ideas/CCI-I-344)
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tf_xla.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tf_xla.md
new file mode 100644
index 0000000000000000000000000000000000000000..0b47d6fbad89d61dd4708285ab7960165e2124ca
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tf_xla.md
@@ -0,0 +1,174 @@
+
+
+# TensorFlow 모델을 위한 XLA 통합 [[xla-integration-for-tensorflow-models]]
+
+[[open-in-colab]]
+
+XLA(Accelerated Linear Algebra)는 TensorFlow 모델의 실행 시간을 가속화하기 위한 컴파일러입니다. [공식 문서](https://www.tensorflow.org/xla)에 따르면 다음과 같습니다:
+
+XLA(Accelerated Linear Algebra)는 선형 대수를 위한 도메인 특화 컴파일러로, TensorFlow 모델을 소스 코드 변경 없이 가속화할 수 있습니다.
+
+TensorFlow에서 XLA를 사용하는 것은 간단합니다. XLA는 `tensorflow` 라이브러리 내에 패키지로 제공되며, [`tf.function`](https://www.tensorflow.org/guide/intro_to_graphs)과 같은 그래프 생성 함수에서 `jit_compile` 인수를 사용하여 활성화할 수 있습니다. `fit()` 및 `predict()`와 같은 Keras 메소드를 사용하는 경우, `jit_compile` 인수를 `model.compile()`에 전달하여 XLA를 간단하게 활성화할 수 있습니다. 그러나 XLA는 이러한 메소드에 국한되지 않고 임의의 `tf.function`을 가속화하는 데에도 사용할 수 있습니다.
+
+🤗 Transformers에서는 [GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2), [T5](https://huggingface.co/docs/transformers/model_doc/t5), [OPT](https://huggingface.co/docs/transformers/model_doc/opt)와 같은 모델의 텍스트 생성, 그리고 [Whisper](https://huggingface.co/docs/transformers/model_doc/whisper)와 같은 모델의 음성 처리를 포함하여 여러 TensorFlow 메소드가 XLA와 호환되도록 다시 작성되었습니다.
+
+정확한 속도 향상은 모델에 따라 다르지만, 🤗 Transformers 내의 TensorFlow 텍스트 생성 모델의 경우 최대 100배의 속도 향상을 확인했습니다. 이 문서에서는 이러한 모델에 대해 XLA를 사용하여 최대 성능을 얻는 방법을 설명합니다. 또한 XLA 통합의 벤치마크 및 디자인 철학에 대한 추가 자료 링크도 제공할 것입니다.
+
+## XLA를 사용하여 TF 함수 실행하기 [[running-tf-functions-with-xla]]
+
+TensorFlow에서 다음과 같은 모델을 고려해 봅시다:
+
+```py
+import tensorflow as tf
+
+model = tf.keras.Sequential(
+ [tf.keras.layers.Dense(10, input_shape=(10,), activation="relu"), tf.keras.layers.Dense(5, activation="softmax")]
+)
+```
+
+위 모델은 차원이 `(10, )`인 입력을 받습니다. 다음과 같이 모델을 사용하여 순전파를 실행할 수 있습니다:
+
+```py
+# 모델에 대한 임의의 입력을 생성합니다.
+batch_size = 16
+input_vector_dim = 10
+random_inputs = tf.random.normal((batch_size, input_vector_dim))
+
+# 순전파를 실행합니다.
+_ = model(random_inputs)
+```
+
+XLA로 컴파일된 함수로 순전파를 실행하려면 다음과 같이 해야 합니다:
+
+```py
+xla_fn = tf.function(model, jit_compile=True)
+_ = xla_fn(random_inputs)
+```
+
+`model`의 기본 `call()` 함수는 XLA 그래프를 컴파일하는 데 사용됩니다. 그러나 다른 모델 함수를 XLA로 컴파일하려면 다음과 같이 할 수도 있습니다:
+
+```py
+my_xla_fn = tf.function(model.my_xla_fn, jit_compile=True)
+```
+
+## 🤗 Transformers에서 XLA를 사용하여 TF 텍스트 생성 모델 실행하기 [[running-a-tf-text-generation-model-with-xla-from-transformers]]
+
+🤗 Transformers에서 XLA로 가속화된 생성을 활성화하려면 최신 버전의 `transformers`가 설치되어 있어야 합니다. 다음과 같이 설치할 수 있습니다:
+
+```bash
+pip install transformers --upgrade
+```
+
+그리고 다음 코드를 실행할 수 있습니다:
+
+```py
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+# 최소 버전의 Transformers가 설치되어 있지 않다면 오류가 발생합니다.
+from transformers.utils import check_min_version
+
+check_min_version("4.21.0")
+
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+input_string = ["TensorFlow is"]
+
+# XLA 생성 함수를 만들기 위한 한 줄
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+tokenized_input = tokenizer(input_string, return_tensors="tf")
+generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+
+decoded_text = tokenizer.decode(generated_tokens[0], skip_special_tokens=True)
+print(f"Generated -- {decoded_text}")
+# Generated -- TensorFlow is an open-source, open-source, distributed-source application # framework for the
+```
+
+알 수 있듯이, `generate()`에서 XLA를 활성화하는 것은 단 한 줄의 코드입니다. 코드의 나머지 부분은 변경되지 않습니다. 그러나 위 코드 스니펫에서는 XLA에 특정한 몇 가지 주의할 점이 있습니다. XLA가 가져다줄 속도 향상을 실현하기 위해서는 이를 알고 있어야 합니다. 다음 섹션에서 이에 대해 논의합니다.
+
+## 주의할 점 [[gotchas-to-be-aware-of]]
+
+XLA 활성화 함수(`xla_generate()`와 같은)를 처음 실행할 때 내부적으로 계산 그래프를 추론하려고 하며, 이는 시간이 소요됩니다. 이 과정은 [“추적(tracing)”](https://www.tensorflow.org/guide/intro_to_graphs#when_is_a_function_tracing)이라고 알려져 있습니다.
+
+생성 시간이 빠르지 않다는 것을 알 수 있을 것입니다. `xla_generate()`(또는 다른 XLA 활성화 함수)의 연속 호출은 함수에 전달된 입력이 초기에 구축된 계산 그래프와 동일한 형태를 따른다면, 계산 그래프를 추론할 필요가 없습니다. 이는 입력 형태가 고정된 모달리티(예: 이미지)에는 문제가 되지 않지만, 가변 입력 형태 모달리티(예: 텍스트)를 사용할 때 주의해야 합니다.
+
+`xla_generate()`가 항상 동일한 입력 형태로 동작하도록 하려면, 토크나이저를 호출할 때 `padding` 인수를 지정할 수 있습니다.
+
+```py
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+input_string = ["TensorFlow is"]
+
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+# 여기서, padding 옵션이 있는 토크나이저를 호출합니다.
+tokenized_input = tokenizer(input_string, pad_to_multiple_of=8, padding=True, return_tensors="tf")
+
+generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+decoded_text = tokenizer.decode(generated_tokens[0], skip_special_tokens=True)
+print(f"Generated -- {decoded_text}")
+```
+
+이렇게 하면 `xla_generate()`에 대한 입력이 항상 추적된 형태로 전달되어 생성 시간이 가속화됩니다. 다음 코드로 이를 확인할 수 있습니다:
+
+```py
+import time
+import tensorflow as tf
+from transformers import AutoTokenizer, TFAutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2", padding_side="left", pad_token="")
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2")
+
+xla_generate = tf.function(model.generate, jit_compile=True)
+
+for input_string in ["TensorFlow is", "TensorFlow is a", "TFLite is a"]:
+ tokenized_input = tokenizer(input_string, pad_to_multiple_of=8, padding=True, return_tensors="tf")
+ start = time.time_ns()
+ generated_tokens = xla_generate(**tokenized_input, num_beams=2)
+ end = time.time_ns()
+ print(f"Execution time -- {(end - start) / 1e6:.1f} ms\n")
+```
+
+Tesla T4 GPU에서는 다음과 같은 출력을 예상할 수 있습니다:
+
+```bash
+Execution time -- 30819.6 ms
+
+Execution time -- 79.0 ms
+
+Execution time -- 78.9 ms
+```
+`xla_generate()`의 첫 번째 호출은 추적 때문에 시간이 오래 걸리지만, 연속 호출은 몇 배나 빠릅니다. 생성 옵션에 대한 어떤 변경이든 다시 추적을 유발하므로 생성 시간이 느려질 수 있음을 명심하세요.
+
+이 문서에서는 🤗 Transformers에서 제공하는 모든 텍스트 생성 옵션을 다루지 않았습니다. 고급 사용 사례에 대해 문서를 참조하시기 바랍니다.
+
+## 추가 자료 [[additional-resources]]
+
+여기에 🤗 Transformers와 XLA에 대해 더 자세히 알고 싶은 경우 도움이 될 수 있는 몇 가지 추가 자료를 제공합니다.
+
+* [이 Colab 노트북](https://colab.research.google.com/github/huggingface/blog/blob/main/notebooks/91_tf_xla_generate.ipynb)은 XLA와 호환되는 인코더-디코더([T5](https://huggingface.co/docs/transformers/model_doc/t5)와 같은) 및 디코더 전용([GPT2](https://huggingface.co/docs/transformers/model_doc/gpt2)와 같은) 텍스트 생성 모델을 실험해 볼 수 있는 대화형 데모를 제공합니다.
+* [이 블로그 글](https://huggingface.co/blog/tf-xla-generate)은 TensorFlow에서 XLA에 대한 친절한 소개와 함께 XLA와 호환되는 모델의 비교 벤치마크에 대한 개요를 제공합니다.
+* [이 블로그 글](https://blog.tensorflow.org/2022/11/how-hugging-face-improved-text-generation-performance-with-xla.html)은 🤗 Transformers의 TensorFlow 모델에 XLA 지원을 추가하는 것에 대한 디자인 철학을 논의합니다.
+* XLA와 TensorFlow 그래프에 대해 더 자세히 알고 싶은 경우 추천하는 글:
+ * [XLA: 기계 학습을 위한 최적화 컴파일러](https://www.tensorflow.org/xla)
+ * [그래프 및 tf.function 소개](https://www.tensorflow.org/guide/intro_to_graphs)
+ * [tf.function으로 성능 향상하기](https://www.tensorflow.org/guide/function)
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tflite.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tflite.md
new file mode 100644
index 0000000000000000000000000000000000000000..464106a6b7c2612b93a25848b750d90f7258e4cd
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tflite.md
@@ -0,0 +1,62 @@
+
+
+# TFLite로 내보내기[[export-to-tflite]]
+
+[TensorFlow Lite](https://www.tensorflow.org/lite/guide)는 자원이 제한된 휴대폰, 임베디드 시스템, 사물인터넷(IoT) 기기에서
+기계학습 모델을 배포하기 위한 경량 프레임워크입니다.
+TFLite는 연산 능력, 메모리, 전력 소비가 제한된 기기에서 모델을 효율적으로 최적화하고 실행하기 위해
+설계되었습니다.
+TensorFlow Lite 모델은 `.tflite` 파일 확장자로 식별되는 특수하고 효율적인 휴대용 포맷으로 표현됩니다.
+
+🤗 Optimum은 `exporters.tflite` 모듈로 🤗 Transformers 모델을 TFLite로 내보내는 기능을 제공합니다.
+지원되는 모델 아키텍처 목록은 [🤗 Optimum 문서](https://huggingface.co/docs/optimum/exporters/tflite/overview)를 참고하세요.
+
+모델을 TFLite로 내보내려면, 필요한 종속성을 설치하세요:
+
+```bash
+pip install optimum[exporters-tf]
+```
+
+모든 사용 가능한 인수를 확인하려면, [🤗 Optimum 문서](https://huggingface.co/docs/optimum/main/en/exporters/tflite/usage_guides/export_a_model)를 참고하거나
+터미널에서 도움말을 살펴보세요:
+
+```bash
+optimum-cli export tflite --help
+```
+
+예를 들어 🤗 Hub에서의 `google-bert/bert-base-uncased` 모델 체크포인트를 내보내려면, 다음 명령을 실행하세요:
+
+```bash
+optimum-cli export tflite --model google-bert/bert-base-uncased --sequence_length 128 bert_tflite/
+```
+
+다음과 같이 진행 상황을 나타내는 로그와 결과물인 `model.tflite`가 저장된 위치를 보여주는 로그가 표시됩니다:
+
+```bash
+Validating TFLite model...
+ -[✓] TFLite model output names match reference model (logits)
+ - Validating TFLite Model output "logits":
+ -[✓] (1, 128, 30522) matches (1, 128, 30522)
+ -[x] values not close enough, max diff: 5.817413330078125e-05 (atol: 1e-05)
+The TensorFlow Lite export succeeded with the warning: The maximum absolute difference between the output of the reference model and the TFLite exported model is not within the set tolerance 1e-05:
+- logits: max diff = 5.817413330078125e-05.
+ The exported model was saved at: bert_tflite
+ ```
+
+위 예제는 🤗 Hub에서의 체크포인트를 내보내는 방법을 보여줍니다.
+로컬 모델을 내보낸다면, 먼저 모델 가중치와 토크나이저 파일이 모두 같은 디렉터리( `local_path` )에 저장됐는지 확인하세요.
+CLI를 사용할 때, 🤗 Hub에서의 체크포인트 이름 대신 `model` 인수에 `local_path`를 전달하면 됩니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tokenizer_summary.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tokenizer_summary.md
new file mode 100644
index 0000000000000000000000000000000000000000..0a4ece29a476d942b6cfc5067f723a301cb2e278
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/tokenizer_summary.md
@@ -0,0 +1,253 @@
+
+
+# 토크나이저 요약[[summary-of-the-tokenizers]]
+
+[[open-in-colab]]
+
+이 페이지에서는 토큰화에 대해 자세히 살펴보겠습니다.
+
+
+
+[데이터 전처리하기 튜토리얼](preprocessing)에서 살펴본 것처럼, 텍스트를 토큰화하는 것은 텍스트를 단어 또는 서브워드로 분할하고 룩업 테이블을 통해 id로 변환하는 과정입니다.
+단어 또는 서브워드를 id로 변환하는 것은 간단하기 때문에 이번 문서에서는 텍스트를 단어 또는 서브워드로 쪼개는 것(즉, 텍스트를 토큰화하는 것)에 중점을 두겠습니다.
+구체적으로, 🤗 Transformers에서 사용되는 세 가지 주요 토큰화 유형인 [Byte-Pair Encoding (BPE)](#byte-pair-encoding), [WordPiece](#wordpiece), [SentencePiece](#sentencepiece)를 살펴보고 어떤 모델에서 어떤 토큰화 유형을 사용하는지 예시를 보여드리겠습니다.
+
+각 모델 페이지에 연결된 토크나이저의 문서를 보면 사전 훈련 모델에서 어떤 토크나이저를 사용했는지 알 수 있습니다.
+예를 들어, [`BertTokenizer`]를 보면 이 모델이 [WordPiece](#wordpiece)를 사용하는 것을 알 수 있습니다.
+
+## 개요[[introduction]]
+
+텍스트를 작은 묶음(chunk)으로 쪼개는 것은 보기보다 어려운 작업이며, 여러 가지 방법이 있습니다.
+예를 들어, `"Don't you love 🤗 Transformers? We sure do."` 라는 문장을 살펴보도록 하겠습니다.
+
+
+
+위 문장을 토큰화하는 간단한 방법은 공백을 기준으로 쪼개는 것입니다.
+토큰화된 결과는 다음과 같습니다:
+
+```
+["Don't", "you", "love", "🤗", "Transformers?", "We", "sure", "do."]
+```
+이는 첫 번째 결과로는 합리적이지만, `"Transformers?"`와 `"do."`토큰을 보면 각각 `"Transformer"`와 `"do"`에 구두점이 붙어있는 것을 확인할 수 있습니다.
+구두점을 고려해야 모델이 단어의 다른 표현과 그 뒤에 올 수 있는 모든 가능한 구두점을 학습할 필요가 없습니다. 그렇지 않으면 모델이 학습해야 하는 표현의 수가 폭발적으로 증가하게 됩니다.
+
+구두점을 고려한 토큰화 결과는 다음과 같습니다:
+
+```
+["Don", "'", "t", "you", "love", "🤗", "Transformers", "?", "We", "sure", "do", "."]
+```
+
+이전보다 나아졌습니다. 하지만, `"Don't"`의 토큰화 결과도 수정이 필요합니다.
+`"Don't"`는 `"do not"`의 줄임말이기 때문에 `["Do", "n't"]`로 토큰화되는 것이 좋습니다.
+여기서부터 복잡해지기 시작합니다. 그리고 이 점이 각 모델마다 고유한 토큰화 유형이 존재하는 이유 중 하나입니다.
+텍스트를 토큰화하는 데 적용하는 규칙에 따라 동일한 텍스트에 대해 토큰화된 결과가 달라집니다.
+사전 훈련된 모델은 훈련 데이터를 토큰화하는 데 사용된 것과 동일한 규칙으로 토큰화된 입력을 제공해야만 제대로 작동합니다.
+
+[spaCy](https://spacy.io/)와 [Moses](http://www.statmt.org/moses/?n=Development.GetStarted)는 유명한 규칙 기반 토크나이저입니다. 예제에 *spaCy*와 *Moses* 를 적용한 결과는 다음과 같습니다:
+
+```
+["Do", "n't", "you", "love", "🤗", "Transformers", "?", "We", "sure", "do", "."]
+```
+
+보시다시피 공백 및 구두점 토큰화와 규칙 기반 토큰화가 사용됩니다.
+공백 및 구두점, 규칙 기반 토큰화은 모두 단어 문장을 단어로 쪼개는 단어 토큰화에 해당합니다.
+이 토큰화 방법은 텍스트를 더 작은 묶음(chunk)로 분할하는 가장 직관적인 방법이지만, 대규모 텍스트 말뭉치에 대해서는 문제가 발생할 수 있습니다.
+이 경우 공백 및 구두점 토큰화는 일반적으로 매우 큰 어휘(사용된 모든 고유 단어와 토큰 집합)을 생성합니다.
+*예를 들어*, [Transformer XL](model_doc/transformerxl)은 공백 및 구두점 토큰화를 사용해 어휘(vocabulary) 크기가 267,735입니다!
+
+어휘 크기가 크면 모델에 입력 및 출력 레이어로 엄청난 임베딩 행렬이 필요하므로 메모리와 시간 복잡성이 모두 증가합니다.
+일반적으로 트랜스포머 모델은 어휘 크기가 50,000개를 넘는 경우가 드물며, 특히 단일 언어에 대해서만 사전 훈련된 경우에는 더욱 그렇습니다.
+단순한 공백과 구두점 토큰화가 만족스럽지 않다면 단순히 문자를 토큰화하면 어떨까요?
+
+
+
+문자 토큰화는 아주 간단하고 메모리와 시간 복잡도를 크게 줄일 수 있지만, 모델이 의미 있는 입력 표현을 학습하기에는 훨씬 더 어렵습니다.
+
+*예를 들어*, 문자 `"t"`에 대한 의미 있는 문맥 독립적 표현을 배우는 것 보다 단어 `"today"`에 대한 의미 있는 문맥 독립적 표현을 배우는 것이 훨씬 더 어렵습니다.
+문자 토큰화는 종종 성능 저하를 동반하기 때문에 두 가지 장점을 모두 얻기 위해 트랜스포머 모델은 **서브워드** 토큰화라고 하는 단어 수준과 문자 수준 토큰화의 하이브리드를 사용합니다.
+
+## 서브워드 토큰화[[subword-tokenization]]
+
+
+
+서브워드 토큰화 알고리즘은 자주 사용되는 단어는 더 작은 하위 단어로 쪼개고, 드문 단어는 의미 있는 하위 단어로 분해되어야 한다는 원칙에 따라 작동합니다.
+예를 들어 `"annoyingly"`는 드문 단어로 간주되어 `"annoying"`과 `"ly"`로 분해될 수 있습니다.
+`"annoyingly"`가 `"annoying"`과 `"ly"`의 합성어인 반면, `"annoying"`과 `"ly"` 둘 다 독립적인 서브워드로 자주 등장합니다.
+이는 터키어와 같은 응집성 언어에서 특히 유용하며, 서브워드를 묶어 임의로 긴 복합 단어를 만들 수 있습니다.
+
+서브워드 토큰화를 사용하면 모델이 의미 있는 문맥 독립적 표현을 학습하면서 합리적인 어휘 크기를 가질 수 있습니다.
+또한, 서브워드 토큰화를 통해 모델은 이전에 본 적이 없는 단어를 알려진 서브워드로 분해하여 처리할 수 있습니다.
+
+예를 들어, [`~transformers.BertTokenizer`]는 `"I have a new GPU!"` 라는 문장을 아래와 같이 토큰화합니다:
+
+```py
+>>> from transformers import BertTokenizer
+
+>>> tokenizer = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+>>> tokenizer.tokenize("I have a new GPU!")
+["i", "have", "a", "new", "gp", "##u", "!"]
+```
+
+대소문자가 없는 모델을 사용해 문장의 시작이 소문자로 표기되었습니다.
+단어 `["i", "have", "a", "new"]`는 토크나이저의 어휘에 속하지만, `"gpu"`는 속하지 않는 것을 확인할 수 있습니다.
+결과적으로 토크나이저는 `"gpu"`를 알려진 두 개의 서브워드로 쪼갭니다: `["gp" and "##u"]`.
+`"##"`은 토큰의 나머지 부분이 공백 없이 이전 토큰에 연결되어야(attach) 함을 의미합니다(토큰화 디코딩 또는 역전을 위해).
+
+또 다른 예로, [`~transformers.XLNetTokenizer`]는 이전에 예시 문장을 다음과 같이 토큰화합니다:
+```py
+>>> from transformers import XLNetTokenizer
+
+>>> tokenizer = XLNetTokenizer.from_pretrained("xlnet/xlnet-base-cased")
+>>> tokenizer.tokenize("Don't you love 🤗 Transformers? We sure do.")
+["▁Don", "'", "t", "▁you", "▁love", "▁", "🤗", "▁", "Transform", "ers", "?", "▁We", "▁sure", "▁do", "."]
+```
+
+`"▁"`가 가지는 의미는 [SentencePiece](#sentencepiece)에서 다시 살펴보도록 하겠습니다.
+보다시피 `"Transformers"` 라는 드문 단어는 서브워드 `"Transform"`와 `"ers"`로 쪼개집니다.
+
+이제 다양한 하위 단어 토큰화 알고리즘이 어떻게 작동하는지 살펴보겠습니다.
+이러한 토큰화 알고리즘은 일반적으로 해당 모델이 학습되는 말뭉치에 대해 수행되는 어떤 형태의 학습에 의존한다는 점에 유의하세요.
+
+
+
+### 바이트 페어 인코딩 (Byte-Pair Encoding, BPE)[[bytepair-encoding-bpe]]
+
+바이트 페어 인코딩(BPE)은 [Neural Machine Translation of Rare Words with Subword Units (Sennrich et
+al., 2015)](https://arxiv.org/abs/1508.07909) 에서 소개되었습니다.
+BPE는 훈련 데이터를 단어로 분할하는 사전 토크나이저(pre-tokenizer)에 의존합니다.
+사전 토큰화(Pretokenization)에는 [GPT-2](model_doc/gpt2), [Roberta](model_doc/roberta)와 같은 간단한 공백 토큰화가 있습니다.
+복잡한 사전 토큰화에는 규칙 기반 토큰화가 해당하는데, 훈련 말뭉치에서 각 단어의 빈도를 계산하기 위해 사용합니다.
+[XLM](model_doc/xlm), 대부분의 언어에서 Moses를 사용하는 [FlauBERT](model_doc/flaubert), Spacy와 ftfy를 사용하는 [GPT](model_doc/gpt)가 해당합니다.
+
+
+사전 토큰화 이후에, 고유 단어 집합가 생성되고 훈련 데이터에서 각 단어가 등장하는 빈도가 결정됩니다.
+다음으로, BPE는 고유 단어 집합에 나타나는 모든 기호로 구성된 기본 어휘를 생성하고 기본 어휘의 두 기호에서 새로운 기호를 형성하는 병합 규칙을 학습합니다.
+어휘가 원하는 어휘 크기에 도달할 때까지 위의 과정을 반복합니다.
+어휘 크기는 토크나이저를 훈련시키기 전에 정의해야 하는 하이퍼파라미터라는 점을 유의하세요.
+
+예를 들어, 사전 토큰화 후 빈도를 포함한 다음과 같은 어휘 집합이 결정되었다고 가정해 보겠습니다:
+
+```
+("hug", 10), ("pug", 5), ("pun", 12), ("bun", 4), ("hugs", 5)
+```
+
+결과적으로 기본 어휘는 `["b", "g", "h", "n", "p", "s", "u"]` 이고, 각 단어를 기본 어휘에 속하는 기호로 쪼개면 아래와 같습니다:
+
+```
+("h" "u" "g", 10), ("p" "u" "g", 5), ("p" "u" "n", 12), ("b" "u" "n", 4), ("h" "u" "g" "s", 5)
+```
+
+그런 다음 BPE는 가능한 각 기호 쌍의 빈도를 계산하여 가장 자주 발생하는 기호 쌍을 선택합니다.
+위의 예시에서 `"h"` 뒤에 오는 `"u"`는 _10 + 5 = 15_ 번 등장합니다. (`"hug"`에서 10번, `"hugs"`에서 5번 등장)
+
+하지만, 가장 등장 빈도가 높은 기호 쌍은 `"u"` 뒤에 오는 `"g"`입니다. _10 + 5 + 5 = 20_ 으로 총 20번 등장합니다.
+따라서 토크나이저가 병합하는 가장 첫 번째 쌍은 `"u"` 뒤에 오는 `"g"`입니다. `"ug"`가 어휘에 추가되어 어휘는 다음과 같습니다:
+
+```
+("h" "ug", 10), ("p" "ug", 5), ("p" "u" "n", 12), ("b" "u" "n", 4), ("h" "ug" "s", 5)
+```
+
+BPE는 다음으로 가장 많이 등장하는 기호 쌍을 식별합니다.
+`"u"` 뒤에 오는 `"n"`은 16번 등장해 `"un"` 으로 병합되어 어휘에 추가됩니다.
+그 다음으로 빈도수가 놓은 기호 쌍은 `"h"` 뒤에 오는 `"ug"`로 15번 등장합니다.
+다시 한 번 `"hug"`로 병합되어 어휘에 추가됩니다.
+
+현재 단계에서 어휘는 `["b", "g", "h", "n", "p", "s", "u", "ug", "un", "hug"]` 이고, 고유 단어 집합은 다음과 같습니다:
+
+```
+("hug", 10), ("p" "ug", 5), ("p" "un", 12), ("b" "un", 4), ("hug" "s", 5)
+```
+
+이 시점에서 바이트 페어 인코딩 훈련이 중단된다고 가정하면, 훈련된 병합 규칙은 새로운 단어에 적용됩니다(기본 어휘에 포함된 기호가 새로운 단어에 포함되지 않는 한).
+예를 들어, 단어 `"bug"`는 `["b", "ug"]`로 토큰화되지만, `"m"`이 기본 어휘에 없기 때문에 `"mug"`는 `["", "ug"]`로 토큰화될 것입니다.
+훈련 데이터에는 단일 문자가 최소한 한 번 등장하기 때문에 일반적으로 `"m"`과 같은 단일 문자는 `""` 기호로 대체되지 않지만, 이모티콘과 같은 특별한 문자인 경우에는 대체될 수 있습니다.
+
+이전에 언급했듯이 어휘 크기(즉 기본 어휘 크기 + 병합 횟수)는 선택해야하는 하이퍼파라미터입니다.
+예를 들어 [GPT](model_doc/gpt)의 기본 어휘 크기는 478, 40,000번의 병합 이후에 훈련을 종료하기 때문에 어휘 크기가 40,478입니다.
+
+#### 바이트 수준 BPE (Byte-level BPE)[[bytelevel-bpe]]
+
+가능한 모든 기본 문자를 포함하는 기본 어휘의 크기는 굉장히 커질 수 있습니다. (예: 모든 유니코드 문자를 기본 문자로 간주하는 경우)
+더 나은 기본 어휘를 갖도록 [GPT-2](https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf)는 기본 어휘로 바이트(bytes)를 사용합니다.
+이 방식은 모든 기본 문자가 어휘에 포함되도록 하면서 기본 어휘의 크기를 256으로 제한합니다.
+구두점을 다루는 추가적인 규칙을 사용해 GPT2 토크나이저는 모든 텍스트를 기호 없이 토큰화할 수 있습니다.
+[GPT-2](model_doc/gpt)의 어휘 크기는 50,257로 256 바이트 크기의 기본 토큰, 특별한 end-of-text 토큰과 50,000번의 병합으로 학습한 기호로 구성됩니다.
+
+
+
+### 워드피스 (WordPiece)[[wordpiece]]
+
+워드피스는 [BERT](model_doc/bert), [DistilBERT](model_doc/distilbert), [Electra](model_doc/electra)에 사용된 서브워드 토큰화 알고리즘입니다.
+이 알고리즘은 [Japanese and Korean Voice Search (Schuster et al., 2012)](https://static.googleusercontent.com/media/research.google.com/ja//pubs/archive/37842.pdf)에서 소개되었고, BPE와 굉장히 유사합니다.
+워드피스는 훈련 데이터에 등장하는 모든 문자로 기본 어휘를 초기화한 후, 주어진 병합 규칙에 따라 점진적으로 학습합니다.
+BPE와는 대조적으로 워드피스는 가장 빈도수가 높은 기호 쌍을 선택하지 않고, 어휘에 추가되었을 때 훈련 데이터의 우도가 최대화되는 쌍을 선택합니다.
+
+정확히 무슨 의미일까요?
+이전 예시를 참조하면, 훈련 데이터의 우도 값을 최대화하는 것은 모든 기호 쌍 중에서 첫 번째 기호와 두 번째 기호의 확률로 나눈 확률이 가장 큰 기호 쌍을 찾는 것과 동일합니다.
+예를 들어 `"ug"`의 확률이 `"u"`와 `"g"` 각각으로 쪼개졌을 때 보다 높아야 `"u"` 뒤에 오는 `"g"`는 병합될 것입니다.
+직관적으로 워드피스는 두 기호를 병합하여 _잃는_ 것을 평가하여 그만한 _가치_가 있는지 확인한다는 점에서 BPE와 약간 다릅니다.
+
+
+
+### 유니그램 (Unigram)[[unigram]]
+
+유니그램은 [Subword Regularization: Improving Neural Network Translation Models with Multiple Subword Candidates (Kudo, 2018)](https://arxiv.org/pdf/1804.10959.pdf)에서 제안된 서브워드 토큰화 알고리즘입니다.
+BPE나 워드피스와 달리 유니그램은 기본 어휘를 많은 수의 기호로 초기화한 후 각 기호를 점진적으로 줄여 더 작은 어휘를 얻습니다.
+예를 들어 기본 어휘는 모든 사전 토큰화된 단어와 가장 일반적인 하위 문자열에 해당할 수 있습니다.
+유니그램은 transformers 모델에서 직접적으로 사용되지는 않지만, [SentencePiece](#sentencepiece)와 함께 사용됩니다.
+
+각 훈련 단계에서 유니그램 알고리즘은 현재 어휘와 유니그램 언어 모델이 주어졌을 때 훈련 데이터에 대한 손실(흔히 로그 우도로 정의됨)을 정의합니다.
+그런 다음 어휘의 각 기호에 대해 알고리즘은 해당 기호를 어휘에서 제거할 경우 전체 손실이 얼마나 증가할지 계산합니다.
+이후에 유니그램은 손실 증가율이 가장 낮은 기호의 p(보통 10% 또는 20%) 퍼센트를 제거합니다. (제거되는 기호는 훈련 데이터에 대한 전체 손실에 가장 작은 영향을 미칩니다.)
+어휘가 원하는 크기에 도달할 때까지 이 과정을 반복합니다.
+유니그램 알고리즘은 항상 기본 문자를 포함해 어떤 단어라도 토큰화할 수 있습니다.
+유니그램이 병합 규칙에 기반하지 않기 떄문에 (BPE나 워드피스와는 대조적으로), 해당 알고리즘은 훈련 이후에 새로운 텍스트를 토큰화하는데 여러 가지 방법이 있습니다.
+
+예를 들어, 훈련된 유니그램 토큰화가 다음과 같은 어휘를 가진다면:
+
+```
+["b", "g", "h", "n", "p", "s", "u", "ug", "un", "hug"],
+```
+
+`"hugs"`는 두 가지로 토큰화할 수 있습니다. `["hug", "s"]`와 `["h", "ug", "s"]` 또는 `["h", "u", "g", "s"]`.
+
+그렇다면 어떤 토큰화 방법을 선택해야 할까요?
+유니그램은 어휘를 저장하는 것 외에도 훈련 말뭉치에 각 토큰의 확률을 저장하여 훈련 후 가능한 각 토큰화의 확률을 계산할 수 있도록 합니다.
+이 알고리즘은 단순히 실제로 가장 가능성이 높은 토큰화를 선택하지만, 확률에 따라 가능한 토큰화를 샘플링할 수 있는 가능성도 제공합니다.
+이러한 확률은 토크나이저가 학습한 손실에 의해 정의됩니다.
+
+단어로 구성된 훈련 데이터를 \\(x_{1}, \dots, x_{N}\\)라 하고, 단어 \\(x_{i}\\)에 대한 가능한 모든 토큰화 결과를 \\(S(x_{i})\\)라 한다면, 전체 손실은 다음과 같이 정의됩니다:
+
+$$\mathcal{L} = -\sum_{i=1}^{N} \log \left ( \sum_{x \in S(x_{i})} p(x) \right )$$
+
+
+
+
+
+### 센텐스피스 (SentencePiece)[[sentencepiece]]
+
+지금까지 다룬 토큰화 알고리즘은 동일한 문제를 가집니다: 입력 텍스트는 공백을 사용하여 단어를 구분한다고 가정합니다.
+하지만, 모든 언어에서 단어를 구분하기 위해 공백을 사용하지 않습니다.
+한가지 가능한 해결방안은 특정 언어에 특화된 사전 토크나이저를 사용하는 것입니다. 예를 들어 [XLM](model_doc/xlm)은 특정 중국어, 일본어, 태국어 사전 토크나이저를 사용합니다.
+이 문제를 일반적인 방법으로 해결하기 위해, [SentencePiece: A simple and language independent subword tokenizer and detokenizer for Neural Text Processing (Kudo et al., 2018)](https://arxiv.org/pdf/1808.06226.pdf)는 입력을 스트림으로 처리해 공백를 하나의 문자로 사용합니다.
+이후에 BPE 또는 유니그램 알고리즘을 사용해 적절한 어휘를 구성합니다.
+
+[`XLNetTokenizer`]는 센텐스피스를 사용하기 때문에, 위에서 다룬 예시에서 어휘에 `"▁"`가 포함되어있습니다.
+모든 토큰을 합친 후 `"▁"`을 공백으로 대체하면 되기 때문에 센텐스피스로 토큰화된 결과는 디코딩하기 수월합니다.
+
+transformers에서 제공하는 센텐스피스 토크나이저를 사용하는 모든 모델은 유니그램과 함께 사용됩니다.
+[ALBERT](model_doc/albert), [XLNet](model_doc/xlnet), [Marian](model_doc/marian), [T5](model_doc/t5) 모델이 센텐스피스 토크나이저를 사용합니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/torchscript.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/torchscript.md
new file mode 100644
index 0000000000000000000000000000000000000000..28e198c5ec9306cf7f91fe2cf3a1b60485b47a26
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/torchscript.md
@@ -0,0 +1,189 @@
+
+
+# TorchScript로 내보내기[[export-to-torchscript]]
+
+
+
+TorchScript를 활용한 실험은 아직 초기 단계로, 가변적인 입력 크기 모델들을 통해 그 기능성을 계속 탐구하고 있습니다.
+이 기능은 저희가 관심을 두고 있는 분야 중 하나이며,
+앞으로 출시될 버전에서 더 많은 코드 예제, 더 유연한 구현, 그리고 Python 기반 코드와 컴파일된 TorchScript를 비교하는 벤치마크를 등을 통해 분석을 심화할 예정입니다.
+
+
+
+[TorchScript 문서](https://pytorch.org/docs/stable/jit.html)에서는 이렇게 말합니다.
+
+> TorchScript는 PyTorch 코드에서 직렬화 및 최적화 가능한 모델을 생성하는 방법입니다.
+
+[JIT과 TRACE](https://pytorch.org/docs/stable/jit.html)는 개발자가 모델을 내보내서 효율 지향적인 C++ 프로그램과 같은 다른 프로그램에서 재사용할 수 있도록 하는 PyTorch 모듈입니다.
+
+PyTorch 기반 Python 프로그램과 다른 환경에서 모델을 재사용할 수 있도록, 🤗 Transformers 모델을 TorchScript로 내보낼 수 있는 인터페이스를 제공합니다.
+이 문서에서는 TorchScript를 사용하여 모델을 내보내고 사용하는 방법을 설명합니다.
+
+모델을 내보내려면 두 가지가 필요합니다:
+
+- `torchscript` 플래그로 모델 인스턴스화
+- 더미 입력을 사용한 순전파(forward pass)
+
+이 필수 조건들은 아래에 자세히 설명된 것처럼 개발자들이 주의해야 할 여러 사항들을 의미합니다.
+
+## TorchScript 플래그와 묶인 가중치(tied weights)[[torchscript-flag-and-tied-weights]]
+
+`torchscript` 플래그가 필요한 이유는 대부분의 🤗 Transformers 언어 모델에서 `Embedding` 레이어와 `Decoding` 레이어 간의 묶인 가중치(tied weights)가 존재하기 때문입니다.
+TorchScript는 묶인 가중치를 가진 모델을 내보낼 수 없으므로, 미리 가중치를 풀고 복제해야 합니다.
+
+`torchscript` 플래그로 인스턴스화된 모델은 `Embedding` 레이어와 `Decoding` 레이어가 분리되어 있으므로 이후에 훈련해서는 안 됩니다.
+훈련을 하게 되면 두 레이어 간 동기화가 해제되어 예상치 못한 결과가 발생할 수 있습니다.
+
+언어 모델 헤드를 갖지 않은 모델은 가중치가 묶여 있지 않아서 이 문제가 발생하지 않습니다.
+이러한 모델들은 `torchscript` 플래그 없이 안전하게 내보낼 수 있습니다.
+
+## 더미 입력과 표준 길이[[dummy-inputs-and-standard-lengths]]
+
+더미 입력(dummy inputs)은 모델의 순전파(forward pass)에 사용됩니다.
+입력 값이 레이어를 통해 전파되는 동안, PyTorch는 각 텐서에서 실행된 다른 연산을 추적합니다.
+이러한 기록된 연산은 모델의 *추적(trace)*을 생성하는 데 사용됩니다.
+
+추적은 입력의 차원을 기준으로 생성됩니다.
+따라서 더미 입력의 차원에 제한되어, 다른 시퀀스 길이나 배치 크기에서는 작동하지 않습니다.
+다른 크기로 시도할 경우 다음과 같은 오류가 발생합니다:
+
+```
+`The expanded size of the tensor (3) must match the existing size (7) at non-singleton dimension 2`
+```
+추론 중 모델에 공급될 가장 큰 입력만큼 큰 더미 입력 크기로 모델을 추적하는 것이 좋습니다.
+패딩은 누락된 값을 채우는 데 도움이 될 수 있습니다.
+그러나 모델이 더 큰 입력 크기로 추적되기 때문에, 행렬의 차원이 커지고 계산량이 많아집니다.
+
+다양한 시퀀스 길이 모델을 내보낼 때는 각 입력에 대해 수행되는 총 연산 횟수에 주의하고 성능을 주의 깊게 확인하세요.
+
+## Python에서 TorchScript 사용하기[[using-torchscript-in-python]]
+
+이 섹션에서는 모델을 저장하고 가져오는 방법, 추적을 사용하여 추론하는 방법을 보여줍니다.
+
+### 모델 저장하기[[saving-a-model]]
+
+`BertModel`을 TorchScript로 내보내려면 `BertConfig` 클래스에서 `BertModel`을 인스턴스화한 다음, `traced_bert.pt`라는 파일명으로 디스크에 저장하면 됩니다.
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+
+enc = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+
+# 입력 텍스트 토큰화하기
+text = "[CLS] Who was Jim Henson ? [SEP] Jim Henson was a puppeteer [SEP]"
+tokenized_text = enc.tokenize(text)
+
+# 입력 토큰 중 하나를 마스킹하기
+masked_index = 8
+tokenized_text[masked_index] = "[MASK]"
+indexed_tokens = enc.convert_tokens_to_ids(tokenized_text)
+segments_ids = [0, 0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 1]
+
+# 더미 입력 만들기
+tokens_tensor = torch.tensor([indexed_tokens])
+segments_tensors = torch.tensor([segments_ids])
+dummy_input = [tokens_tensor, segments_tensors]
+
+# torchscript 플래그로 모델 초기화하기
+# 이 모델은 LM 헤드가 없으므로 필요하지 않지만, 플래그를 True로 설정합니다.
+config = BertConfig(
+ vocab_size_or_config_json_file=32000,
+ hidden_size=768,
+ num_hidden_layers=12,
+ num_attention_heads=12,
+ intermediate_size=3072,
+ torchscript=True,
+)
+
+# 모델을 인스턴트화하기
+model = BertModel(config)
+
+# 모델을 평가 모드로 두어야 합니다.
+model.eval()
+
+# 만약 *from_pretrained*를 사용하여 모델을 인스턴스화하는 경우, TorchScript 플래그를 쉽게 설정할 수 있습니다
+model = BertModel.from_pretrained("google-bert/bert-base-uncased", torchscript=True)
+
+# 추적 생성하기
+traced_model = torch.jit.trace(model, [tokens_tensor, segments_tensors])
+torch.jit.save(traced_model, "traced_bert.pt")
+```
+
+### 모델 가져오기[[loading-a-model]]
+
+이제 이전에 저장한 `BertModel`, 즉 `traced_bert.pt`를 디스크에서 가져오고, 이전에 초기화한 `dummy_input`에서 사용할 수 있습니다.
+
+```python
+loaded_model = torch.jit.load("traced_bert.pt")
+loaded_model.eval()
+
+all_encoder_layers, pooled_output = loaded_model(*dummy_input)
+```
+
+### 추적된 모델을 사용하여 추론하기[[using-a-traced-model-for-inference]]
+
+`__call__` 이중 언더스코어(dunder) 메소드를 사용하여 추론에 추적된 모델을 사용하세요:
+
+```python
+traced_model(tokens_tensor, segments_tensors)
+```
+
+## Neuron SDK로 Hugging Face TorchScript 모델을 AWS에 배포하기[[deploy-hugging-face-torchscript-models-to-aws-with-the-neuron-sdk]]
+
+AWS가 클라우드에서 저비용, 고성능 머신 러닝 추론을 위한 [Amazon EC2 Inf1](https://aws.amazon.com/ec2/instance-types/inf1/) 인스턴스 제품군을 출시했습니다.
+Inf1 인스턴스는 딥러닝 추론 워크로드에 특화된 맞춤 하드웨어 가속기인 AWS Inferentia 칩으로 구동됩니다.
+[AWS Neuron](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/#)은 Inferentia를 위한 SDK로, Inf1에 배포하기 위한 transformers 모델 추적 및 최적화를 지원합니다.
+Neuron SDK는 다음과 같은 기능을 제공합니다:
+
+1. 코드 한 줄만 변경하면 클라우드 추론를 위해 TorchScript 모델을 추적하고 최적화할 수 있는 쉬운 API
+2. 즉시 사용 가능한 성능 최적화로 [비용 효율 향상](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/benchmark/>)
+3. [PyTorch](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/bert_tutorial/tutorial_pretrained_bert.html) 또는 [TensorFlow](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/tensorflow/huggingface_bert/huggingface_bert.html)로 구축된 Hugging Face transformers 모델 지원
+
+### 시사점[[implications]]
+
+[BERT (Bidirectional Encoder Representations from Transformers)](https://huggingface.co/docs/transformers/main/model_doc/bert) 아키텍처 또는 그 변형인 [distilBERT](https://huggingface.co/docs/transformers/main/model_doc/distilbert) 및 [roBERTa](https://huggingface.co/docs/transformers/main/model_doc/roberta)를 기반으로 한 Transformers 모델은 추출 기반 질의응답, 시퀀스 분류 및 토큰 분류와 같은 비생성 작업 시 Inf1에서 최상의 성능을 보입니다.
+그러나 텍스트 생성 작업도 [AWS Neuron MarianMT 튜토리얼](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/src/examples/pytorch/transformers-marianmt.html)을 따라 Inf1에서 실행되도록 조정할 수 있습니다.
+
+Inferentia에서 바로 변환할 수 있는 모델에 대한 자세한 정보는 Neuron 문서의 [Model Architecture Fit](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/models/models-inferentia.html#models-inferentia) 섹션에서 확인할 수 있습니다.
+
+### 종속성[[dependencies]]
+
+AWS Neuron을 사용하여 모델을 변환하려면 [Neuron SDK 환경](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/neuron-guide/neuron-frameworks/pytorch-neuron/index.html#installation-guide)이 필요합니다.
+ 이는 [AWS Deep Learning AMI](https://docs.aws.amazon.com/dlami/latest/devguide/tutorial-inferentia-launching.html)에 미리 구성되어 있습니다.
+
+### AWS Neuron으로 모델 변환하기[[converting-a-model-for-aws-neuron]]
+
+`BertModel`을 추적하려면, [Python에서 TorchScript 사용하기](torchscript#using-torchscript-in-python)에서와 동일한 코드를 사용해서 AWS NEURON용 모델을 변환합니다.
+`torch.neuron` 프레임워크 익스텐션을 가져와 Python API를 통해 Neuron SDK의 구성 요소에 접근합니다:
+
+```python
+from transformers import BertModel, BertTokenizer, BertConfig
+import torch
+import torch.neuron
+```
+
+다음 줄만 수정하면 됩니다:
+
+```diff
+- torch.jit.trace(model, [tokens_tensor, segments_tensors])
++ torch.neuron.trace(model, [token_tensor, segments_tensors])
+```
+
+이로써 Neuron SDK가 모델을 추적하고 Inf1 인스턴스에 최적화할 수 있게 됩니다.
+
+AWS Neuron SDK의 기능, 도구, 예제 튜토리얼 및 최신 업데이트에 대해 자세히 알아보려면 [AWS NeuronSDK 문서](https://awsdocs-neuron.readthedocs-hosted.com/en/latest/index.html)를 참조하세요.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/trainer.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/trainer.md
new file mode 100644
index 0000000000000000000000000000000000000000..976072730c869888bd99b9b3e9cc974a4190cfd5
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/trainer.md
@@ -0,0 +1,619 @@
+
+
+# Trainer [[trainer]]
+
+[`Trainer`]는 Transformers 라이브러리에 구현된 PyTorch 모델을 반복하여 훈련 및 평가 과정입니다. 훈련에 필요한 요소(모델, 토크나이저, 데이터셋, 평가 함수, 훈련 하이퍼파라미터 등)만 제공하면 [`Trainer`]가 필요한 나머지 작업을 처리합니다. 이를 통해 직접 훈련 루프를 작성하지 않고도 빠르게 훈련을 시작할 수 있습니다. 또한 [`Trainer`]는 강력한 맞춤 설정과 다양한 훈련 옵션을 제공하여 사용자 맞춤 훈련이 가능합니다.
+
+
+
+Transformers는 [`Trainer`] 클래스 외에도 번역이나 요약과 같은 시퀀스-투-시퀀스 작업을 위한 [`Seq2SeqTrainer`] 클래스도 제공합니다. 또한 [TRL](https://hf.co/docs/trl) 라이브러리에는 [`Trainer`] 클래스를 감싸고 Llama-2 및 Mistral과 같은 언어 모델을 자동 회귀 기법으로 훈련하는 데 최적화된 [`~trl.SFTTrainer`] 클래스 입니다. [`~trl.SFTTrainer`]는 시퀀스 패킹, LoRA, 양자화 및 DeepSpeed와 같은 기능을 지원하여 크기 상관없이 모델 효율적으로 확장할 수 있습니다.
+
+
+
+이들 다른 [`Trainer`] 유형 클래스에 대해 더 알고 싶다면 [API 참조](./main_classes/trainer)를 확인하여 언제 어떤 클래스가 적합할지 얼마든지 확인하세요. 일반적으로 [`Trainer`]는 가장 다재다능한 옵션으로, 다양한 작업에 적합합니다. [`Seq2SeqTrainer`]는 시퀀스-투-시퀀스 작업을 위해 설계되었고, [`~trl.SFTTrainer`]는 언어 모델 훈련을 위해 설계되었습니다.
+
+
+
+시작하기 전에, 분산 환경에서 PyTorch 훈련과 실행을 할 수 있게 [Accelerate](https://hf.co/docs/accelerate) 라이브러리가 설치되었는지 확인하세요.
+
+```bash
+pip install accelerate
+
+# 업그레이드
+pip install accelerate --upgrade
+```
+
+이 가이드는 [`Trainer`] 클래스에 대한 개요를 제공합니다.
+
+## 기본 사용법 [[basic-usage]]
+
+[`Trainer`]는 기본적인 훈련 루프에 필요한 모든 코드를 포함하고 있습니다.
+
+1. 손실을 계산하는 훈련 단계를 수행합니다.
+2. [`~accelerate.Accelerator.backward`] 메소드로 그레이디언트를 계산합니다.
+3. 그레이디언트를 기반으로 가중치를 업데이트합니다.
+4. 정해진 에폭 수에 도달할 때까지 이 과정을 반복합니다.
+
+[`Trainer`] 클래스는 PyTorch와 훈련 과정에 익숙하지 않거나 막 시작한 경우에도 훈련이 가능하도록 필요한 모든 코드를 추상화하였습니다. 또한 매번 훈련 루프를 손수 작성하지 않아도 되며, 훈련에 필요한 모델과 데이터셋 같은 필수 구성 요소만 제공하면, [Trainer] 클래스가 나머지를 처리합니다.
+
+훈련 옵션이나 하이퍼파라미터를 지정하려면, [`TrainingArguments`] 클래스에서 확인 할 수 있습니다. 예를 들어, 모델을 저장할 디렉토리를 `output_dir`에 정의하고, 훈련 후에 Hub로 모델을 푸시하려면 `push_to_hub=True`로 설정합니다.
+
+```py
+from transformers import TrainingArguments
+
+training_args = TrainingArguments(
+ output_dir="your-model",
+ learning_rate=2e-5,
+ per_device_train_batch_size=16,
+ per_device_eval_batch_size=16,
+ num_train_epochs=2,
+ weight_decay=0.01,
+ eval_strategy="epoch",
+ save_strategy="epoch",
+ load_best_model_at_end=True,
+ push_to_hub=True,
+)
+```
+
+`training_args`를 [`Trainer`]에 모델, 데이터셋, 데이터셋 전처리 도구(데이터 유형에 따라 토크나이저, 특징 추출기 또는 이미지 프로세서일 수 있음), 데이터 수집기 및 훈련 중 확인할 지표를 계산할 함수를 함께 전달하세요.
+
+마지막으로, [`~Trainer.train`]를 호출하여 훈련을 시작하세요!
+
+```py
+from transformers import Trainer
+
+trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=dataset["train"],
+ eval_dataset=dataset["test"],
+ tokenizer=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics,
+)
+
+trainer.train()
+```
+
+### 체크포인트 [[checkpoints]]
+
+[`Trainer`] 클래스는 [`TrainingArguments`]의 `output_dir` 매개변수에 지정된 디렉토리에 모델 체크포인트를 저장합니다. 체크포인트는 `checkpoint-000` 하위 폴더에 저장되며, 여기서 끝의 숫자는 훈련 단계에 해당합니다. 체크포인트를 저장하면 나중에 훈련을 재개할 때 유용합니다.
+
+```py
+# 최신 체크포인트에서 재개
+trainer.train(resume_from_checkpoint=True)
+
+# 출력 디렉토리에 저장된 특정 체크포인트에서 재개
+trainer.train(resume_from_checkpoint="your-model/checkpoint-1000")
+```
+
+체크포인트를 Hub에 푸시하려면 [`TrainingArguments`]에서 `push_to_hub=True`로 설정하여 커밋하고 푸시할 수 있습니다. 체크포인트 저장 방법을 결정하는 다른 옵션은 [`hub_strategy`](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.hub_strategy) 매개변수에서 설정합니다:
+
+* `hub_strategy="checkpoint"`는 최신 체크포인트를 "last-checkpoint"라는 하위 폴더에 푸시하여 훈련을 재개할 수 있습니다.
+* `hub_strategy="all_checkpoints"`는 모든 체크포인트를 `output_dir`에 정의된 디렉토리에 푸시합니다(모델 리포지토리에서 폴더당 하나의 체크포인트를 볼 수 있습니다).
+
+체크포인트에서 훈련을 재개할 때, [`Trainer`]는 체크포인트가 저장될 때와 동일한 Python, NumPy 및 PyTorch RNG 상태를 유지하려고 합니다. 하지만 PyTorch는 기본 설정으로 '일관된 결과를 보장하지 않음'으로 많이 되어있기 때문에, RNG 상태가 동일할 것이라고 보장할 수 없습니다. 따라서, 일관된 결과가 보장되도록 활성화 하려면, [랜덤성 제어](https://pytorch.org/docs/stable/notes/randomness#controlling-sources-of-randomness) 가이드를 참고하여 훈련을 완전히 일관된 결과를 보장 받도록 만들기 위해 활성화할 수 있는 항목을 확인하세요. 다만, 특정 설정을 결정적으로 만들면 훈련이 느려질 수 있습니다.
+
+## Trainer 맞춤 설정 [[customize-the-trainer]]
+
+[`Trainer`] 클래스는 접근성과 용이성을 염두에 두고 설계되었지만, 더 다양한 기능을 원하는 사용자들을 위해 다양한 맞춤 설정 옵션을 제공합니다. [`Trainer`]의 많은 메소드는 서브클래스화 및 오버라이드하여 원하는 기능을 제공할 수 있으며, 이를 통해 전체 훈련 루프를 다시 작성할 필요 없이 원하는 기능을 추가할 수 있습니다. 이러한 메소드에는 다음이 포함됩니다:
+
+* [`~Trainer.get_train_dataloader`]는 훈련 데이터로더를 생성합니다.
+* [`~Trainer.get_eval_dataloader`]는 평가 데이터로더를 생성합니다.
+* [`~Trainer.get_test_dataloader`]는 테스트 데이터로더를 생성합니다.
+* [`~Trainer.log`]는 훈련을 모니터링하는 다양한 객체에 대한 정보를 로그로 남깁니다.
+* [`~Trainer.create_optimizer_and_scheduler`]는 `__init__`에서 전달되지 않은 경우 옵티마이저와 학습률 스케줄러를 생성합니다. 이들은 각각 [`~Trainer.create_optimizer`] 및 [`~Trainer.create_scheduler`]로 별도로 맞춤 설정 할 수 있습니다.
+* [`~Trainer.compute_loss`]는 훈련 입력 배치에 대한 손실을 계산합니다.
+* [`~Trainer.training_step`]는 훈련 단계를 수행합니다.
+* [`~Trainer.prediction_step`]는 예측 및 테스트 단계를 수행합니다.
+* [`~Trainer.evaluate`]는 모델을 평가하고 평가 지표을 반환합니다.
+* [`~Trainer.predict`]는 테스트 세트에 대한 예측(레이블이 있는 경우 지표 포함)을 수행합니다.
+
+예를 들어, [`~Trainer.compute_loss`] 메소드를 맞춤 설정하여 가중 손실을 사용하려는 경우:
+
+```py
+from torch import nn
+from transformers import Trainer
+
+class CustomTrainer(Trainer):
+ def compute_loss(self,
+
+ model, inputs, return_outputs=False):
+ labels = inputs.pop("labels")
+ # 순방향 전파
+ outputs = model(**inputs)
+ logits = outputs.get("logits")
+ # 서로 다른 가중치로 3개의 레이블에 대한 사용자 정의 손실을 계산
+ loss_fct = nn.CrossEntropyLoss(weight=torch.tensor([1.0, 2.0, 3.0], device=model.device))
+ loss = loss_fct(logits.view(-1, self.model.config.num_labels), labels.view(-1))
+ return (loss, outputs) if return_outputs else loss
+```
+
+### 콜백 [[callbacks]]
+
+[`Trainer`]를 맞춤 설정하는 또 다른 방법은 [콜백](callbacks)을 사용하는 것입니다. 콜백은 훈련 루프에서 *변화를 주지 않습니다*. 훈련 루프의 상태를 검사한 후 상태에 따라 일부 작업(조기 종료, 결과 로그 등)을 실행합니다. 즉, 콜백은 사용자 정의 손실 함수와 같은 것을 구현하는 데 사용할 수 없으며, 이를 위해서는 [`~Trainer.compute_loss`] 메소드를 서브클래스화하고 오버라이드해야 합니다.
+
+예를 들어, 훈련 루프에 10단계 후 조기 종료 콜백을 추가하려면 다음과 같이 합니다.
+
+```py
+from transformers import TrainerCallback
+
+class EarlyStoppingCallback(TrainerCallback):
+ def __init__(self, num_steps=10):
+ self.num_steps = num_steps
+
+ def on_step_end(self, args, state, control, **kwargs):
+ if state.global_step >= self.num_steps:
+ return {"should_training_stop": True}
+ else:
+ return {}
+```
+
+그런 다음, 이를 [`Trainer`]의 `callback` 매개변수에 전달합니다.
+
+```py
+from transformers import Trainer
+
+trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=dataset["train"],
+ eval_dataset=dataset["test"],
+ tokenizer=tokenizer,
+ data_collator=data_collator,
+ compute_metrics=compute_metrics,
+ callbacks=[EarlyStoppingCallback()],
+)
+```
+
+## 로깅 [[logging]]
+
+
+
+로깅 API에 대한 자세한 내용은 [로깅](./main_classes/logging) API 레퍼런스를 확인하세요.
+
+
+
+[`Trainer`]는 기본적으로 `logging.INFO`로 설정되어 있어 오류, 경고 및 기타 기본 정보를 보고합니다. 분산 환경에서는 [`Trainer`] 복제본이 `logging.WARNING`으로 설정되어 오류와 경고만 보고합니다. [`TrainingArguments`]의 [`log_level`](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.log_level) 및 [`log_level_replica`](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments.log_level_replica) 매개변수로 로그 레벨을 변경할 수 있습니다.
+
+각 노드의 로그 레벨 설정을 구성하려면 [`log_on_each_node`](https://huggingface.co/docs/transformers/main/en/main_classes/trainer#transformers.TrainingArguments.log_on_each_node) 매개변수를 사용하여 각 노드에서 로그 레벨을 사용할지 아니면 주 노드에서만 사용할지 결정하세요.
+
+
+
+[`Trainer`]는 [`Trainer.__init__`] 메소드에서 각 노드에 대해 로그 레벨을 별도로 설정하므로, 다른 Transformers 기능을 사용할 경우 [`Trainer`] 객체를 생성하기 전에 이를 미리 설정하는 것이 좋습니다.
+
+
+
+예를 들어, 메인 코드와 모듈을 각 노드에 따라 동일한 로그 레벨을 사용하도록 설정하려면 다음과 같이 합니다.
+
+```py
+logger = logging.getLogger(__name__)
+
+logging.basicConfig(
+ format="%(asctime)s - %(levelname)s - %(name)s - %(message)s",
+ datefmt="%m/%d/%Y %H:%M:%S",
+ handlers=[logging.StreamHandler(sys.stdout)],
+)
+
+log_level = training_args.get_process_log_level()
+logger.setLevel(log_level)
+datasets.utils.logging.set_verbosity(log_level)
+transformers.utils.logging.set_verbosity(log_level)
+
+trainer = Trainer(...)
+```
+
+각 노드에서 기록될 내용을 구성하기 위해 `log_level`과 `log_level_replica`를 다양한 조합으로 사용해보세요.
+
+
+
+
+```bash
+my_app.py ... --log_level warning --log_level_replica error
+```
+
+
+
+
+멀티 노드 환경에서는 `log_on_each_node 0` 매개변수를 추가합니다.
+
+```bash
+my_app.py ... --log_level warning --log_level_replica error --log_on_each_node 0
+
+# 오류만 보고하도록 설정
+my_app.py ... --log_level error --log_level_replica error --log_on_each_node 0
+```
+
+
+
+
+## NEFTune [[neftune]]
+
+[NEFTune](https://hf.co/papers/2310.05914)은 훈련 중 임베딩 벡터에 노이즈를 추가하여 성능을 향상시킬 수 있는 기술입니다. [`Trainer`]에서 이를 활성화하려면 [`TrainingArguments`]의 `neftune_noise_alpha` 매개변수를 설정하여 노이즈의 양을 조절합니다.
+
+```py
+from transformers import TrainingArguments, Trainer
+
+training_args = TrainingArguments(..., neftune_noise_alpha=0.1)
+trainer = Trainer(..., args=training_args)
+```
+
+NEFTune은 예상치 못한 동작을 피할 목적으로 처음 임베딩 레이어로 복원하기 위해 훈련 후 비활성화 됩니다.
+
+## GaLore [[galore]]
+
+Gradient Low-Rank Projection (GaLore)은 전체 매개변수를 학습하면서도 LoRA와 같은 일반적인 저계수 적응 방법보다 더 메모리 효율적인 저계수 학습 전략입니다.
+
+먼저 GaLore 공식 리포지토리를 설치합니다:
+
+```bash
+pip install galore-torch
+```
+
+그런 다음 `optim`에 `["galore_adamw", "galore_adafactor", "galore_adamw_8bit"]` 중 하나와 함께 `optim_target_modules`를 추가합니다. 이는 적용하려는 대상 모듈 이름에 해당하는 문자열, 정규 표현식 또는 전체 경로의 목록일 수 있습니다. 아래는 end-to-end 예제 스크립트입니다(필요한 경우 `pip install trl datasets`를 실행):
+
+```python
+import torch
+import datasets
+import trl
+
+from transformers import TrainingArguments, AutoConfig, AutoTokenizer, AutoModelForCausalLM
+
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+args = TrainingArguments(
+ output_dir="./test-galore",
+ max_steps=100,
+ per_device_train_batch_size=2,
+ optim="galore_adamw",
+ optim_target_modules=["attn", "mlp"]
+)
+
+model_id = "google/gemma-2b"
+
+config = AutoConfig.from_pretrained(model_id)
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_config(config).to(0)
+
+trainer = trl.SFTTrainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+ dataset_text_field='text',
+ max_seq_length=512,
+)
+
+trainer.train()
+```
+
+GaLore가 지원하는 추가 매개변수를 전달하려면 `optim_args`를 설정합니다. 예를 들어:
+
+```python
+import torch
+import datasets
+import trl
+
+from transformers import TrainingArguments, AutoConfig, AutoTokenizer, AutoModelForCausalLM
+
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+args = TrainingArguments(
+ output_dir="./test-galore",
+ max_steps=100,
+ per_device_train_batch_size=2,
+ optim="galore_adamw",
+ optim_target_modules=["attn", "mlp"],
+ optim_args="rank=64, update_proj_gap=100, scale=0.10",
+)
+
+model_id = "google/gemma-2b"
+
+config = AutoConfig.from_pretrained(model_id)
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_config(config).to(0)
+
+trainer = trl.SFTTrainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+ dataset_text_field='text',
+ max_seq_length=512,
+)
+
+trainer.train()
+```
+
+해당 방법에 대한 자세한 내용은 [원본 리포지토리](https://github.com/jiaweizzhao/GaLore) 또는 [논문](https://arxiv.org/abs/2403.03507)을 참고하세요.
+
+현재 GaLore 레이어로 간주되는 Linear 레이어만 훈련 할수 있으며, 저계수 분해를 사용하여 훈련되고 나머지 레이어는 기존 방식으로 최적화됩니다.
+
+훈련 시작 전에 시간이 약간 걸릴 수 있습니다(NVIDIA A100에서 2B 모델의 경우 약 3분), 하지만 이후 훈련은 원활하게 진행됩니다.
+
+다음과 같이 옵티마이저 이름에 `layerwise`를 추가하여 레이어별 최적화를 수행할 수도 있습니다:
+
+```python
+import torch
+import datasets
+import trl
+
+from transformers import TrainingArguments, AutoConfig, AutoTokenizer, AutoModelForCausalLM
+
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+args = TrainingArguments(
+ output_dir="./test-galore",
+ max_steps=100,
+ per_device_train_batch_size=2,
+ optim="galore_adamw_layerwise",
+ optim_target_modules=["attn", "mlp"]
+)
+
+model_id = "google/gemma-2b"
+
+config = AutoConfig.from_pretrained(model_id)
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_config(config).to(0)
+
+trainer = trl.SFTTrainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+ dataset_text_field='text',
+ max_seq_length=512,
+)
+
+trainer.train()
+```
+
+레이어별 최적화는 다소 실험적이며 DDP(분산 데이터 병렬)를 지원하지 않으므로, 단일 GPU에서만 훈련 스크립트를 실행할 수 있습니다. 자세한 내용은 [이 문서를](https://github.com/jiaweizzhao/GaLore?tab=readme-ov-file#train-7b-model-with-a-single-gpu-with-24gb-memory)을 참조하세요. gradient clipping, DeepSpeed 등 다른 기능은 기본적으로 지원되지 않을 수 있습니다. 이러한 문제가 발생하면 [GitHub에 이슈를 올려주세요](https://github.com/huggingface/transformers/issues).
+
+## LOMO 옵티마이저 [[lomo-optimizer]]
+
+LOMO 옵티마이저는 [제한된 자원으로 대형 언어 모델의 전체 매개변수 미세 조정](https://hf.co/papers/2306.09782)과 [적응형 학습률을 통한 저메모리 최적화(AdaLomo)](https://hf.co/papers/2310.10195)에서 도입되었습니다.
+이들은 모두 효율적인 전체 매개변수 미세 조정 방법으로 구성되어 있습니다. 이러한 옵티마이저들은 메모리 사용량을 줄이기 위해 그레이디언트 계산과 매개변수 업데이트를 하나의 단계로 융합합니다. LOMO에서 지원되는 옵티마이저는 `"lomo"`와 `"adalomo"`입니다. 먼저 pypi에서 `pip install lomo-optim`를 통해 `lomo`를 설치하거나, GitHub 소스에서 `pip install git+https://github.com/OpenLMLab/LOMO.git`로 설치하세요.
+
+
+
+저자에 따르면, `grad_norm` 없이 `AdaLomo`를 사용하는 것이 더 나은 성능과 높은 처리량을 제공한다고 합니다.
+
+
+
+다음은 IMDB 데이터셋에서 [google/gemma-2b](https://huggingface.co/google/gemma-2b)를 최대 정밀도로 미세 조정하는 간단한 스크립트입니다:
+
+```python
+import torch
+import datasets
+from transformers import TrainingArguments, AutoTokenizer, AutoModelForCausalLM
+import trl
+
+train_dataset = datasets.load_dataset('imdb', split='train')
+
+args = TrainingArguments(
+ output_dir="./test-lomo",
+ max_steps=1000,
+ per_device_train_batch_size=4,
+ optim="adalomo",
+ gradient_checkpointing=True,
+ logging_strategy="steps",
+ logging_steps=1,
+ learning_rate=2e-6,
+ save_strategy="no",
+ run_name="lomo-imdb",
+)
+
+model_id = "google/gemma-2b"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForCausalLM.from_pretrained(model_id, low_cpu_mem_usage=True).to(0)
+
+trainer = trl.SFTTrainer(
+ model=model,
+ args=args,
+ train_dataset=train_dataset,
+ dataset_text_field='text',
+ max_seq_length=1024,
+)
+
+trainer.train()
+```
+
+## Accelerate와 Trainer [[accelerate-and-trainer]]
+
+[`Trainer`] 클래스는 [Accelerate](https://hf.co/docs/accelerate)로 구동되며, 이는 [FullyShardedDataParallel (FSDP)](https://pytorch.org/blog/introducing-pytorch-fully-sharded-data-parallel-api/) 및 [DeepSpeed](https://www.deepspeed.ai/)와 같은 통합을 지원하는 분산 환경에서 PyTorch 모델을 쉽게 훈련할 수 있는 라이브러리입니다.
+
+
+
+FSDP 샤딩 전략, CPU 오프로드 및 [`Trainer`]와 함께 사용할 수 있는 더 많은 기능을 알아보려면 [Fully Sharded Data Parallel](fsdp) 가이드를 확인하세요.
+
+
+
+[`Trainer`]와 Accelerate를 사용하려면 [`accelerate.config`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-config) 명령을 실행하여 훈련 환경을 설정하세요. 이 명령은 훈련 스크립트를 실행할 때 사용할 `config_file.yaml`을 생성합니다. 예를 들어, 다음 예시는 설정할 수 있는 일부 구성 예입니다.
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+distributed_type: MULTI_GPU
+downcast_bf16: 'no'
+gpu_ids: all
+machine_rank: 0 # 노드에 따라 순위를 변경하세요
+main_process_ip: 192.168.20.1
+main_process_port: 9898
+main_training_function: main
+mixed_precision: fp16
+num_machines: 2
+num_processes: 8
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+distributed_type: FSDP
+downcast_bf16: 'no'
+fsdp_config:
+ fsdp_auto_wrap_policy: TRANSFORMER_BASED_WRAP
+ fsdp_backward_prefetch_policy: BACKWARD_PRE
+ fsdp_forward_prefetch: true
+ fsdp_offload_params: false
+ fsdp_sharding_strategy: 1
+ fsdp_state_dict_type: FULL_STATE_DICT
+ fsdp_sync_module_states: true
+ fsdp_transformer_layer_cls_to_wrap: BertLayer
+ fsdp_use_orig_params: true
+machine_rank: 0
+main_training_function: main
+mixed_precision: bf16
+num_machines: 1
+num_processes: 2
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ deepspeed_config_file: /home/user/configs/ds_zero3_config.json
+ zero3_init_flag: true
+distributed_type: DEEPSPEED
+downcast_bf16: 'no'
+machine_rank: 0
+main_training_function: main
+num_machines: 1
+num_processes: 4
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+deepspeed_config:
+ gradient_accumulation_steps: 1
+ gradient_clipping: 0.7
+ offload_optimizer_device: cpu
+ offload_param_device: cpu
+ zero3_init_flag: true
+ zero_stage: 2
+distributed_type: DEEPSPEED
+downcast_bf16: 'no'
+machine_rank: 0
+main_training_function: main
+mixed_precision: bf16
+num_machines: 1
+num_processes: 4
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+```
+
+
+
+
+```yml
+compute_environment: LOCAL_MACHINE
+tp_config:
+ tp_size: 4
+distributed_type: TP
+downcast_bf16: 'no'
+machine_rank: 0
+main_training_function: main
+mixed_precision: 'no'
+num_machines: 1
+num_processes: 4
+rdzv_backend: static
+same_network: true
+tpu_env: []
+tpu_use_cluster: false
+tpu_use_sudo: false
+use_cpu: false
+
+```
+
+
+
+
+[`accelerate_launch`](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-launch) 명령은 Accelerate와 [`Trainer`]를 사용하여 분산 시스템에서 훈련 스크립트를 실행하는 권장 방법이며, `config_file.yaml`에 지정된 매개변수를 사용합니다. 이 파일은 Accelerate 캐시 폴더에 저장되며 `accelerate_launch`를 실행할 때 자동으로 로드됩니다.
+
+예를 들어, FSDP 구성을 사용하여 [run_glue.py](https://github.com/huggingface/transformers/blob/f4db565b695582891e43a5e042e5d318e28f20b8/examples/pytorch/text-classification/run_glue.py#L4) 훈련 스크립트를 실행하려면 다음과 같이 합니다:
+
+```bash
+accelerate launch \
+ ./examples/pytorch/text-classification/run_glue.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 16 \
+ --learning_rate 5e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/ \
+ --overwrite_output_dir
+```
+
+`config_file.yaml` 파일의 매개변수를 직접 지정할 수도 있습니다:
+
+```bash
+accelerate launch --num_processes=2 \
+ --use_fsdp \
+ --mixed_precision=bf16 \
+ --fsdp_auto_wrap_policy=TRANSFORMER_BASED_WRAP \
+ --fsdp_transformer_layer_cls_to_wrap="BertLayer" \
+ --fsdp_sharding_strategy=1 \
+ --fsdp_state_dict_type=FULL_STATE_DICT \
+ ./examples/pytorch/text-classification/run_glue.py \
+ --model_name_or_path google-bert/bert-base-cased \
+ --task_name $TASK_NAME \
+ --do_train \
+ --do_eval \
+ --max_seq_length 128 \
+ --per_device_train_batch_size 16 \
+ --learning_rate 5e-5 \
+ --num_train_epochs 3 \
+ --output_dir /tmp/$TASK_NAME/ \
+ --overwrite_output_dir
+```
+
+`accelerate_launch`와 사용자 정의 구성에 대해 더 알아보려면 [Accelerate 스크립트 실행](https://huggingface.co/docs/accelerate/basic_tutorials/launch) 튜토리얼을 확인하세요.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/training.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/training.md
new file mode 100644
index 0000000000000000000000000000000000000000..432ba186c3df0c36e298fee6fb0c939c6f206a6e
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/training.md
@@ -0,0 +1,428 @@
+
+
+# 사전 학습된 모델 미세 튜닝하기[[finetune-a-pretrained-model]]
+
+[[open-in-colab]]
+
+사전 학습된 모델을 사용하면 상당한 이점이 있습니다. 계산 비용과 탄소발자국을 줄이고, 처음부터 모델을 학습시킬 필요 없이 최신 모델을 사용할 수 있습니다. 🤗 Transformers는 다양한 작업을 위해 사전 학습된 수천 개의 모델에 액세스할 수 있습니다. 사전 학습된 모델을 사용하는 경우, 자신의 작업과 관련된 데이터셋을 사용해 학습합니다. 이것은 미세 튜닝이라고 하는 매우 강력한 훈련 기법입니다. 이 튜토리얼에서는 당신이 선택한 딥러닝 프레임워크로 사전 학습된 모델을 미세 튜닝합니다:
+
+* 🤗 Transformers로 사전 학습된 모델 미세 튜닝하기 [`Trainer`].
+* Keras를 사용하여 TensorFlow에서 사전 학습된 모델을 미세 튜닝하기.
+* 기본 PyTorch에서 사전 학습된 모델을 미세 튜닝하기.
+
+
+
+## 데이터셋 준비[[prepare-a-dataset]]
+
+
+
+사전 학습된 모델을 미세 튜닝하기 위해서 데이터셋을 다운로드하고 훈련할 수 있도록 준비하세요. 이전 튜토리얼에서 훈련을 위해 데이터를 처리하는 방법을 보여드렸는데, 지금이 배울 걸 되짚을 기회입니다!
+
+먼저 [Yelp 리뷰](https://huggingface.co/datasets/yelp_review_full) 데이터 세트를 로드합니다:
+
+```py
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("yelp_review_full")
+>>> dataset["train"][100]
+{'label': 0,
+ 'text': 'My expectations for McDonalds are t rarely high. But for one to still fail so spectacularly...that takes something special!\\nThe cashier took my friends\'s order, then promptly ignored me. I had to force myself in front of a cashier who opened his register to wait on the person BEHIND me. I waited over five minutes for a gigantic order that included precisely one kid\'s meal. After watching two people who ordered after me be handed their food, I asked where mine was. The manager started yelling at the cashiers for \\"serving off their orders\\" when they didn\'t have their food. But neither cashier was anywhere near those controls, and the manager was the one serving food to customers and clearing the boards.\\nThe manager was rude when giving me my order. She didn\'t make sure that I had everything ON MY RECEIPT, and never even had the decency to apologize that I felt I was getting poor service.\\nI\'ve eaten at various McDonalds restaurants for over 30 years. I\'ve worked at more than one location. I expect bad days, bad moods, and the occasional mistake. But I have yet to have a decent experience at this store. It will remain a place I avoid unless someone in my party needs to avoid illness from low blood sugar. Perhaps I should go back to the racially biased service of Steak n Shake instead!'}
+```
+
+텍스트를 처리하고 서로 다른 길이의 시퀀스 패딩 및 잘라내기 전략을 포함하려면 토크나이저가 필요합니다. 데이터셋을 한 번에 처리하려면 🤗 Dataset [`map`](https://huggingface.co/docs/datasets/process#map) 메서드를 사용하여 전체 데이터셋에 전처리 함수를 적용하세요:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
+
+
+>>> def tokenize_function(examples):
+... return tokenizer(examples["text"], padding="max_length", truncation=True)
+
+
+>>> tokenized_datasets = dataset.map(tokenize_function, batched=True)
+```
+
+필요한 경우 미세 튜닝을 위해 데이터셋의 작은 부분 집합을 만들어 미세 튜닝 작업 시간을 줄일 수 있습니다:
+
+```py
+>>> small_train_dataset = tokenized_datasets["train"].shuffle(seed=42).select(range(1000))
+>>> small_eval_dataset = tokenized_datasets["test"].shuffle(seed=42).select(range(1000))
+```
+
+
+
+## Train
+
+여기서부터는 사용하려는 프레임워크에 해당하는 섹션을 따라야 합니다. 오른쪽 사이드바의 링크를 사용하여 원하는 프레임워크로 이동할 수 있으며, 특정 프레임워크의 모든 콘텐츠를 숨기려면 해당 프레임워크 블록의 오른쪽 상단에 있는 버튼을 사용하면 됩니다!
+
+
+
+
+
+## 파이토치 Trainer로 훈련하기[[train-with-pytorch-trainer]]
+
+🤗 Transformers는 🤗 Transformers 모델 훈련에 최적화된 [`Trainer`] 클래스를 제공하여 훈련 루프를 직접 작성하지 않고도 쉽게 훈련을 시작할 수 있습니다. [`Trainer`] API는 로깅(logging), 경사 누적(gradient accumulation), 혼합 정밀도(mixed precision) 등 다양한 훈련 옵션과 기능을 지원합니다.
+
+먼저 모델을 가져오고 예상되는 레이블 수를 지정합니다. Yelp 리뷰 [데이터셋 카드](https://huggingface.co/datasets/yelp_review_full#data-fields)에서 5개의 레이블이 있음을 알 수 있습니다:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-cased", num_labels=5)
+```
+
+
+
+사전 훈련된 가중치 중 일부가 사용되지 않고 일부 가중치가 무작위로 표시된다는 경고가 표시됩니다.
+걱정마세요. 이것은 올바른 동작입니다! 사전 학습된 BERT 모델의 헤드는 폐기되고 무작위로 초기화된 분류 헤드로 대체됩니다. 이제 사전 학습된 모델의 지식으로 시퀀스 분류 작업을 위한 새로운 모델 헤드를 미세 튜닝 합니다.
+
+
+
+### 하이퍼파라미터 훈련[[training-hyperparameters]]
+
+다음으로 정할 수 있는 모든 하이퍼파라미터와 다양한 훈련 옵션을 활성화하기 위한 플래그를 포함하는 [`TrainingArguments`] 클래스를 생성합니다.
+
+이 튜토리얼에서는 기본 훈련 [하이퍼파라미터](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments)로 시작하지만, 자유롭게 실험하여 여러분들에게 맞는 최적의 설정을 찾을 수 있습니다.
+
+훈련에서 체크포인트(checkpoints)를 저장할 위치를 지정합니다:
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(output_dir="test_trainer")
+```
+
+### 평가 하기[[evaluate]]
+
+[`Trainer`]는 훈련 중에 모델 성능을 자동으로 평가하지 않습니다. 평가 지표를 계산하고 보고할 함수를 [`Trainer`]에 전달해야 합니다.
+[🤗 Evaluate](https://huggingface.co/docs/evaluate/index) 라이브러리는 [`evaluate.load`](https://huggingface.co/spaces/evaluate-metric/accuracy) 함수로 로드할 수 있는 간단한 [`accuracy`]함수를 제공합니다 (자세한 내용은 [둘러보기](https://huggingface.co/docs/evaluate/a_quick_tour)를 참조하세요):
+
+```py
+>>> import numpy as np
+>>> import evaluate
+
+>>> metric = evaluate.load("accuracy")
+```
+
+`metric`에서 [`~evaluate.compute`]를 호출하여 예측의 정확도를 계산합니다. 예측을 `compute`에 전달하기 전에 예측을 로짓으로 변환해야 합니다(모든 🤗 Transformers 모델은 로짓으로 반환한다는 점을 기억하세요):
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... predictions = np.argmax(logits, axis=-1)
+... return metric.compute(predictions=predictions, references=labels)
+```
+
+미세 튜닝 중에 평가 지표를 모니터링하려면 훈련 인수에 `eval_strategy` 파라미터를 지정하여 각 에폭이 끝날 때 평가 지표를 확인할 수 있습니다:
+
+```py
+>>> from transformers import TrainingArguments, Trainer
+
+>>> training_args = TrainingArguments(output_dir="test_trainer", eval_strategy="epoch")
+```
+
+### 훈련 하기[[trainer]]
+
+모델, 훈련 인수, 훈련 및 테스트 데이터셋, 평가 함수가 포함된 [`Trainer`] 객체를 만듭니다:
+
+```py
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... )
+```
+
+그리고 [`~transformers.Trainer.train`]을 호출하여 모델을 미세 튜닝합니다:
+
+```py
+>>> trainer.train()
+```
+
+
+
+
+
+
+## Keras로 텐서플로우 모델 훈련하기[[train-a-tensorflow-model-with-keras]]
+
+Keras API를 사용하여 텐서플로우에서 🤗 Transformers 모델을 훈련할 수도 있습니다!
+
+### Keras용 데이터 로드[[loading-data-for-keras]]
+
+Keras API로 🤗 Transformers 모델을 학습시키려면 데이터셋을 Keras가 이해할 수 있는 형식으로 변환해야 합니다.
+데이터 세트가 작은 경우, 전체를 NumPy 배열로 변환하여 Keras로 전달하면 됩니다.
+더 복잡한 작업을 수행하기 전에 먼저 이 작업을 시도해 보겠습니다.
+
+먼저 데이터 세트를 로드합니다. [GLUE 벤치마크](https://huggingface.co/datasets/glue)의 CoLA 데이터 세트를 사용하겠습니다.
+간단한 바이너리 텍스트 분류 작업이므로 지금은 훈련 데이터 분할만 사용합니다.
+
+```py
+from datasets import load_dataset
+
+dataset = load_dataset("glue", "cola")
+dataset = dataset["train"] # Just take the training split for now
+```
+
+다음으로 토크나이저를 로드하고 데이터를 NumPy 배열로 토큰화합니다. 레이블은 이미 0과 1로 된 리스트이기 때문에 토큰화하지 않고 바로 NumPy 배열로 변환할 수 있습니다!
+
+```py
+from transformers import AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
+tokenized_data = tokenizer(dataset["sentence"], return_tensors="np", padding=True)
+# Tokenizer returns a BatchEncoding, but we convert that to a dict for Keras
+tokenized_data = dict(tokenized_data)
+
+labels = np.array(dataset["label"]) # Label is already an array of 0 and 1
+```
+
+마지막으로 모델을 로드, [`compile`](https://keras.io/api/models/model_training_apis/#compile-method), [`fit`](https://keras.io/api/models/model_training_apis/#fit-method)합니다:
+
+```py
+from transformers import TFAutoModelForSequenceClassification
+from tensorflow.keras.optimizers import Adam
+
+# Load and compile our model
+model = TFAutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-cased")
+# Lower learning rates are often better for fine-tuning transformers
+model.compile(optimizer=Adam(3e-5))
+
+model.fit(tokenized_data, labels)
+```
+
+
+
+모델을 `compile()`할 때 손실 인수를 모델에 전달할 필요가 없습니다!
+이 인수를 비워두면 허깅 페이스 모델은 작업과 모델 아키텍처에 적합한 손실을 자동으로 선택합니다.
+원한다면 언제든지 직접 손실을 지정하여 이를 재정의할 수 있습니다!
+
+
+
+이 접근 방식은 소규모 데이터 집합에서는 잘 작동하지만, 대규모 데이터 집합에서는 문제가 될 수 있습니다. 왜 그럴까요?
+토큰화된 배열과 레이블을 메모리에 완전히 로드하고 NumPy는 "들쭉날쭉한" 배열을 처리하지 않기 때문에,
+모든 토큰화된 샘플을 전체 데이터셋에서 가장 긴 샘플의 길이만큼 패딩해야 합니다. 이렇게 하면 배열이 훨씬 더 커지고 이 패딩 토큰으로 인해 학습 속도도 느려집니다!
+
+### 데이터를 tf.data.Dataset으로 로드하기[[loading-data-as-a-tfdatadataset]]
+
+학습 속도가 느려지는 것을 피하려면 데이터를 `tf.data.Dataset`으로 로드할 수 있습니다. 원한다면 직접
+`tf.data` 파이프라인을 직접 작성할 수도 있지만, 이 작업을 간편하게 수행하는 수 있는 두 가지 방법이 있습니다:
+
+- [`~TFPreTrainedModel.prepare_tf_dataset`]: 대부분의 경우 이 방법을 권장합니다. 모델의 메서드이기 때문에 모델을 검사하여 모델 입력으로 사용할 수 있는 열을 자동으로 파악하고
+나머지는 버려서 더 단순하고 성능이 좋은 데이터 집합을 만들 수 있습니다.
+- [`~datasets.Dataset.to_tf_dataset`]: 이 방법은 좀 더 낮은 수준이며, 포함할 '열'과 '레이블'을 정확히 지정하여
+데이터셋을 생성하는 방법을 정확히 제어하고 싶을 때 유용하며, 포함할 'columns'과 'label_cols'을 정확히 지정할 수 있습니다.
+
+[`~TFPreTrainedModel.prepare_tf_dataset`]을 사용하려면 먼저 다음 코드 샘플과 같이 토크나이저 출력을 데이터 세트에 열로 추가해야 합니다:
+
+```py
+def tokenize_dataset(data):
+ # Keys of the returned dictionary will be added to the dataset as columns
+ return tokenizer(data["text"])
+
+
+dataset = dataset.map(tokenize_dataset)
+```
+
+허깅 페이스 데이터셋은 기본적으로 디스크에 저장되므로 메모리 사용량을 늘리지 않는다는 점을 기억하세요!
+열이 추가되면 데이터셋에서 배치를 스트리밍하고 각 배치에 패딩을 추가할 수 있으므로 전체 데이터셋에 패딩을 추가하는 것보다 패딩 토큰의 수를 크게 줄일 수 있습니다.
+
+
+```py
+>>> tf_dataset = model.prepare_tf_dataset(dataset, batch_size=16, shuffle=True, tokenizer=tokenizer)
+```
+
+위의 코드 샘플에서는 배치가 로드될 때 올바르게 패딩할 수 있도록 `prepare_tf_dataset`에 토크나이저를 전달해야 합니다.
+데이터셋의 모든 샘플 길이가 같고 패딩이 필요하지 않은 경우 이 인수를 건너뛸 수 있습니다.
+샘플을 채우는 것보다 더 복잡한 작업(예: 마스킹된 언어의 토큰 손상 모델링)을 수행하기 위해 토큰을 손상시켜야 하는 경우,
+`collate_fn` 인수를 사용하여 샘플 목록을 배치로 변환하고 원하는 전처리를 적용할 함수를 전달할 수 있습니다.
+[예시](https://github.com/huggingface/transformers/tree/main/examples) 또는
+[노트북](https://huggingface.co/docs/transformers/notebooks)을 참조하여 이 접근 방식이 실제로 작동하는 모습을 확인하세요.
+
+`tf.data.Dataset`을 생성한 후에는 이전과 마찬가지로 모델을 컴파일하고 훈련(fit)할 수 있습니다:
+
+```py
+model.compile(optimizer=Adam(3e-5))
+
+model.fit(tf_dataset)
+```
+
+
+
+
+
+
+## 기본 파이토치로 훈련하기[[train-in-native-pytorch]]
+
+
+
+
+
+[`Trainer`]는 훈련 루프를 처리하며 한 줄의 코드로 모델을 미세 조정할 수 있습니다. 직접 훈련 루프를 작성하는 것을 선호하는 사용자의 경우, 기본 PyTorch에서 🤗 Transformers 모델을 미세 조정할 수도 있습니다.
+
+이 시점에서 노트북을 다시 시작하거나 다음 코드를 실행해 메모리를 확보해야 할 수 있습니다:
+
+```py
+del model
+del trainer
+torch.cuda.empty_cache()
+```
+
+다음으로, '토큰화된 데이터셋'을 수동으로 후처리하여 훈련련에 사용할 수 있도록 준비합니다.
+
+1. 모델이 원시 텍스트를 입력으로 허용하지 않으므로 `text` 열을 제거합니다:
+
+ ```py
+ >>> tokenized_datasets = tokenized_datasets.remove_columns(["text"])
+ ```
+
+2. 모델에서 인수의 이름이 `labels`로 지정될 것으로 예상하므로 `label` 열의 이름을 `labels`로 변경합니다:
+
+ ```py
+ >>> tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+ ```
+
+3. 데이터셋의 형식을 List 대신 PyTorch 텐서를 반환하도록 설정합니다:
+
+ ```py
+ >>> tokenized_datasets.set_format("torch")
+ ```
+
+그리고 앞서 표시된 대로 데이터셋의 더 작은 하위 집합을 생성하여 미세 조정 속도를 높입니다:
+
+```py
+>>> small_train_dataset = tokenized_datasets["train"].shuffle(seed=42).select(range(1000))
+>>> small_eval_dataset = tokenized_datasets["test"].shuffle(seed=42).select(range(1000))
+```
+
+### DataLoader[[dataloader]]
+
+훈련 및 테스트 데이터셋에 대한 'DataLoader'를 생성하여 데이터 배치를 반복할 수 있습니다:
+
+```py
+>>> from torch.utils.data import DataLoader
+
+>>> train_dataloader = DataLoader(small_train_dataset, shuffle=True, batch_size=8)
+>>> eval_dataloader = DataLoader(small_eval_dataset, batch_size=8)
+```
+
+예측을 위한 레이블 개수를 사용하여 모델을 로드합니다:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-cased", num_labels=5)
+```
+
+### 옵티마이저 및 학습 속도 스케줄러[[optimizer-and-learning-rate-scheduler]]
+
+옵티마이저와 학습 속도 스케줄러를 생성하여 모델을 미세 조정합니다. 파이토치에서 제공하는 [`AdamW`](https://pytorch.org/docs/stable/generated/torch.optim.AdamW.html) 옵티마이저를 사용해 보겠습니다:
+
+```py
+>>> from torch.optim import AdamW
+
+>>> optimizer = AdamW(model.parameters(), lr=5e-5)
+```
+
+[`Trainer`]에서 기본 학습 속도 스케줄러를 생성합니다:
+
+```py
+>>> from transformers import get_scheduler
+
+>>> num_epochs = 3
+>>> num_training_steps = num_epochs * len(train_dataloader)
+>>> lr_scheduler = get_scheduler(
+... name="linear", optimizer=optimizer, num_warmup_steps=0, num_training_steps=num_training_steps
+... )
+```
+
+마지막으로, GPU에 액세스할 수 있는 경우 'device'를 지정하여 GPU를 사용하도록 합니다. 그렇지 않으면 CPU에서 훈련하며 몇 분이 아닌 몇 시간이 걸릴 수 있습니다.
+
+```py
+>>> import torch
+
+>>> device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+>>> model.to(device)
+```
+
+
+
+[Colaboratory](https://colab.research.google.com/) 또는 [SageMaker StudioLab](https://studiolab.sagemaker.aws/)과 같은 호스팅 노트북이 없는 경우 클라우드 GPU에 무료로 액세스할 수 있습니다.
+
+
+
+이제 훈련할 준비가 되었습니다! 🥳
+
+### 훈련 루프[[training-loop]]
+
+훈련 진행 상황을 추적하려면 [tqdm](https://tqdm.github.io/) 라이브러리를 사용하여 트레이닝 단계 수에 진행률 표시줄을 추가하세요:
+
+```py
+>>> from tqdm.auto import tqdm
+
+>>> progress_bar = tqdm(range(num_training_steps))
+
+>>> model.train()
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... outputs = model(**batch)
+... loss = outputs.loss
+... loss.backward()
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+### 평가 하기[[evaluate]]
+
+[`Trainer`]에 평가 함수를 추가한 방법과 마찬가지로, 훈련 루프를 직접 작성할 때도 동일한 작업을 수행해야 합니다. 하지만 이번에는 각 에포크가 끝날 때마다 평가지표를 계산하여 보고하는 대신, [`~evaluate.add_batch`]를 사용하여 모든 배치를 누적하고 맨 마지막에 평가지표를 계산합니다.
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("accuracy")
+>>> model.eval()
+>>> for batch in eval_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... with torch.no_grad():
+... outputs = model(**batch)
+
+... logits = outputs.logits
+... predictions = torch.argmax(logits, dim=-1)
+... metric.add_batch(predictions=predictions, references=batch["labels"])
+
+>>> metric.compute()
+```
+
+
+
+
+
+## 추가 자료[[additional-resources]]
+
+더 많은 미세 튜닝 예제는 다음을 참조하세요:
+
+- [🤗 Trnasformers 예제](https://github.com/huggingface/transformers/tree/main/examples)에는 PyTorch 및 텐서플로우에서 일반적인 NLP 작업을 훈련할 수 있는 스크립트가 포함되어 있습니다.
+
+- [🤗 Transformers 노트북](notebooks)에는 PyTorch 및 텐서플로우에서 특정 작업을 위해 모델을 미세 튜닝하는 방법에 대한 다양한 노트북이 포함되어 있습니다.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/transformers_agents.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/transformers_agents.md
new file mode 100644
index 0000000000000000000000000000000000000000..eeb00761e9a7775e9d17315772680478b3aa99dc
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/transformers_agents.md
@@ -0,0 +1,328 @@
+
+
+# Transformers Agent [[transformers-agent]]
+
+
+
+Transformers Agent는 실험 중인 API로 언제든지 변경될 수 있습니다.
+API 또는 기반 모델이 변경되기 쉽기 때문에 에이전트가 반환하는 결과도 달라질 수 있습니다.
+
+
+
+Transformers 버전 4.29.0.에서 *도구*와 *에이전트*라는 컨셉을 도입했습니다. [이 colab](https://colab.research.google.com/drive/1c7MHD-T1forUPGcC_jlwsIptOzpG3hSj)에서 사용해볼 수 있습니다.
+
+간단히 말하면, Agent는 트랜스포머 위에 자연어 API를 제공합니다.
+엄선된 도구 세트를 정의하고, 자연어를 해석하여 이러한 도구를 사용할 수 있는 에이전트를 설계했습니다.
+이 API는 확장이 가능하도록 설계 되었습니다.
+주요 도구를 선별해두었지만, 커뮤니티에서 개발한 모든 도구를 사용할 수 있도록 시스템을 쉽게 확장할 수 있는 방법도 보여드리겠습니다.
+
+몇 가지 예를 통해 새로운 API로 무엇을 할 수 있는지 살펴보겠습니다.
+이 API는 특히 멀티모달 작업에서 강력하므로 이미지를 생성하고 텍스트를 소리내어 읽어보겠습니다.
+
+```py
+agent.run("Caption the following image", image=image)
+```
+
+| **Input** | **Output** |
+|-----------------------------------------------------------------------------------------------------------------------------|-----------------------------------|
+| | A beaver is swimming in the water |
+
+---
+
+```py
+agent.run("Read the following text out loud", text=text)
+```
+| **Input** | **Output** |
+|-------------------------------------------------------------------------------------------------------------------------|----------------------------------------------|
+| A beaver is swimming in the water |
+
+---
+
+```py
+agent.run(
+ "In the following `document`, where will the TRRF Scientific Advisory Council Meeting take place?",
+ document=document,
+)
+```
+| **Input** | **Output** |
+|-----------------------------------------------------------------------------------------------------------------------------|----------------|
+| | ballroom foyer |
+
+## 바로 시작하기 [[quickstart]]
+
+`agent.run`을 사용하려면 먼저 대규모 언어 모델(LLM)인 에이전트를 인스턴스화해야 합니다.
+저희는 openAI 모델뿐만 아니라 BigCode 및 OpenAssistant의 오픈소스 대체 모델도 지원합니다.
+openAI 모델의 성능이 더 우수하지만(단, openAI API 키가 필요하므로 무료로 사용할 수 없음),
+Hugging Face는 BigCode와 OpenAssistant 모델의 엔드포인트에 대한 무료 액세스를 제공하고 있습니다.
+
+우선 모든 기본 종속성을 설치하려면 `agents`를 추가로 설치하세요.
+```bash
+pip install transformers[agents]
+```
+
+openAI 모델을 사용하려면 `openai` 종속성을 설치한 후 [`OpenAiAgent`]를 인스턴스화합니다:
+
+```bash
+pip install openai
+```
+
+
+```py
+from transformers import OpenAiAgent
+
+agent = OpenAiAgent(model="text-davinci-003", api_key="")
+```
+
+BigCode 또는 OpenAssistant를 사용하려면 먼저 로그인하여 Inference API에 액세스하세요:
+
+```py
+from huggingface_hub import login
+
+login("")
+```
+
+그런 다음 에이전트를 인스턴스화합니다.
+
+```py
+from transformers import HfAgent
+
+# Starcoder
+agent = HfAgent("https://api-inference.huggingface.co/models/bigcode/starcoder")
+# StarcoderBase
+# agent = HfAgent("https://api-inference.huggingface.co/models/bigcode/starcoderbase")
+# OpenAssistant
+# agent = HfAgent(url_endpoint="https://api-inference.huggingface.co/models/OpenAssistant/oasst-sft-4-pythia-12b-epoch-3.5")
+```
+
+현재 Hugging Face에서 무료로 제공하는 추론 API를 사용하고 있습니다.
+이 모델에 대한 자체 추론 엔드포인트가 있는 경우(또는 다른 엔드포인트가 있는 경우) 위의 URL을 해당 URL 엔드포인트로 바꿀 수 있습니다.
+
+
+
+StarCoder와 OpenAssistant는 무료로 사용할 수 있으며 간단한 작업에서 놀라울 정도로 잘 작동합니다.
+그러나 더 복잡한 프롬프트를 처리할 때는 체크포인트가 잘 작동하지 않습니다.
+이러한 문제가 발생하면 OpenAI 모델을 사용해 보시기 바랍니다. 아쉽게도 오픈소스는 아니지만 현재로서는 더 나은 성능을 제공합니다.
+
+
+
+이제 준비가 완료되었습니다! 이제 자유롭게 사용할 수 있는 두 가지 API에 대해 자세히 알아보겠습니다.
+
+### 단일 실행 (run) [[single-execution-(run)]]
+
+단일 실행 방법은 에이전트의 [`~Agent.run`] 메소드를 사용하는 경우입니다:
+
+```py
+agent.run("Draw me a picture of rivers and lakes.")
+```
+
+
+
+수행하려는 작업에 적합한 도구를 자동으로 선택하여 적절하게 실행합니다.
+동일한 명령어에서 하나 또는 여러 개의 작업을 수행할 수 있습니다
+(다만, 명령어가 복잡할수록 에이전트가 실패할 가능성이 높아집니다).
+
+```py
+agent.run("Draw me a picture of the sea then transform the picture to add an island")
+```
+
+
+
+
+
+
+모든 [`~Agent.run`] 작업은 독립적이므로 다른 작업으로 여러 번 연속해서 실행할 수 있습니다.
+
+`agent`는 큰 언어 모델일 뿐이므로 프롬프트에 약간의 변화를 주면 완전히 다른 결과가 나올 수 있다는 점에 유의하세요.
+수행하려는 작업을 최대한 명확하게 설명하는 것이 중요합니다.
+좋은 프롬프트를 작성하는 방법은 [여기](custom_tools#writing-good-user-inputs)에서 자세히 확인할 수 있습니다.
+
+여러 실행에 걸쳐 상태를 유지하거나 텍스트가 아닌 개체를 에이전트에게 전달하려는 경우에는 에이전트가 사용할 변수를 지정할 수 있습니다.
+예를 들어 강과 호수의 첫 번째 이미지를 생성한 뒤,
+모델이 해당 그림에 섬을 추가하도록 다음과 같이 요청할 수 있습니다:
+
+```python
+picture = agent.run("Generate a picture of rivers and lakes.")
+updated_picture = agent.run("Transform the image in `picture` to add an island to it.", picture=picture)
+```
+
+
+
+이 방법은 모델이 요청을 이해하지 못하고 도구를 혼합할 때 유용할 수 있습니다. 예를 들면 다음과 같습니다:
+
+```py
+agent.run("Draw me the picture of a capybara swimming in the sea")
+```
+
+여기서 모델은 두 가지 방식으로 해석할 수 있습니다:
+- `text-to-image`이 바다에서 헤엄치는 카피바라를 생성하도록 합니다.
+- 또는 `text-to-image`이 카피바라를 생성한 다음 `image-transformation` 도구를 사용하여 바다에서 헤엄치도록 합니다.
+
+첫 번째 시나리오를 강제로 실행하려면 프롬프트를 인수로 전달하여 실행할 수 있습니다:
+
+```py
+agent.run("Draw me a picture of the `prompt`", prompt="a capybara swimming in the sea")
+```
+
+
+
+
+### 대화 기반 실행 (chat) [[chat-based-execution-(chat)]]
+
+에이전트는 [`~Agent.chat`] 메소드를 사용하는 대화 기반 접근 방식도 있습니다:
+
+```py
+agent.chat("Generate a picture of rivers and lakes")
+```
+
+
+
+```py
+agent.chat("Transform the picture so that there is a rock in there")
+```
+
+
+
+
+
+이 방식은 여러 명령어에 걸쳐 상태를 유지하고자 할 때 흥미로운 접근 방식입니다.
+실험용으로 더 좋지만 복잡한 명령어보다는
+단일 명령어([`~Agent.run`] 메소드가 더 잘 처리하는 명령어)에 훨씬 더 잘 작동하는 경향이 있습니다.
+
+이 메소드는 텍스트가 아닌 유형이나 특정 프롬프트를 전달하려는 경우 인수를 받을 수도 있습니다.
+
+### ⚠️ 원격 실행 [[remote-execution]]
+
+데모 목적과 모든 설정에서 사용할 수 있도록
+에이전트가 접근할 수 있는 몇 가지 기본 도구에 대한 원격 실행기를 만들었습니다.
+이러한 도구는 [inference endpoints](https://huggingface.co/inference-endpoints)를 사용하여 만들어졌습니다.
+원격 실행기 도구를 직접 설정하는 방법을 보려면 [사용자 정의 도구 가이드](./custom_tools)를 읽어보시기 바랍니다.
+
+원격 도구로 실행하려면 [`~Agent.run`] 또는 [`~Agent.chat`] 중 하나에 `remote=True`를 지정하기만 하면 됩니다.
+
+예를 들어 다음 명령은 많은 RAM이나 GPU 없이도 모든 장치에서 효율적으로 실행할 수 있습니다:
+
+```py
+agent.run("Draw me a picture of rivers and lakes", remote=True)
+```
+
+[`~Agent.chat`]도 마찬가지입니다:
+
+```py
+agent.chat("Draw me a picture of rivers and lakes", remote=True)
+```
+
+### 여기서 무슨 일이 일어나는 거죠? 도구란 무엇이고, 에이전트란 무엇인가요? [[whats-happening-here-what-are-tools-and-what-are-agents]]
+
+
+
+#### 에이전트 [[agents]]
+
+여기서 "에이전트"는 대규모 언어 모델이며, 특정 도구 모음에 접근할 수 있도록 프롬프트하고 있습니다.
+
+LLM은 작은 코드 샘플을 생성하는 데 상당히 능숙하므로,
+이 장점을 활용해 도구 모음을 사용하여 작업을 수행하는 작은 코드 샘플을 제공하라는 메시지를 표시합니다.
+그런 다음 에이전트에게 제공하는 작업과 제공하는 도구에 대한 설명으로 이 프롬프트가 완료됩니다.
+이렇게 하면 사용 중인 도구들의 문서에 접근할 수 있으며, 해당 도구들의 입력과 출력을 예상하고, 관련된 코드를 생성할 수 있습니다.
+
+#### 도구 [[tools]]
+
+도구는 매우 간단합니다. 이름과 설명이 있는 단일 기능으로 구성되어 있습니다.
+그런 다음 이러한 도구의 설명을 사용하여 상담원에게 프롬프트를 표시합니다.
+이 프롬프트를 통해 상담원에게 쿼리에서 요청된 작업을 수행하기 위해 도구를 활용하는 방법을 보여줍니다.
+
+에이전트가 매우 원자적인 도구를 사용하여 더 나은 코드를 작성하기 때문에 파이프라인이 아닌 완전히 새로운 도구를 사용합니다.
+파이프라인은 더 많이 리팩터링되며 종종 여러 작업을 하나로 결합합니다.
+도구는 하나의 매우 간단한 작업에만 집중하도록 되어 있습니다.
+
+#### 코드 실행?! [[code-execution]]
+
+그런 다음 이 코드는 도구와 함께 전달된 입력 세트에 대해 작은 Python 인터프리터를 사용하여 실행됩니다.
+"임의 코드 실행이라니!"이라고 비명을 지르는 소리가 들리겠지만, 그렇지 않은 이유를 설명하겠습니다.
+
+호출할 수 있는 함수는 제공한 도구와 인쇄 기능뿐이므로 이미 실행할 수 있는 기능이 제한되어 있습니다.
+Hugging Face 도구로 제한되어 있다면 안전할 것입니다.
+
+그리고 어트리뷰트 조회나 가져오기를 허용하지 않으므로
+(어차피 작은 함수 집합에 입/출력을 전달할 때는 필요하지 않아야 합니다)
+가장 명백한 공격(어차피 LLM에 출력하라는 메시지를 표시해야 합니다)은 문제가 되지 않습니다.
+매우 안전하게 하고 싶다면 추가 인수 return_code=True를 사용하여 run() 메소드를 실행하면 됩니다.
+이 경우 에이전트가 실행할 코드를 반환하고 실행할지 여부를 결정할 수 있습니다.
+
+불법적인 연산을 수행하려고 하거나 에이전트가 생성한 코드에 일반적인 파이썬 오류가 있는 경우
+실행이 중지됩니다.
+
+### 엄선된 도구 모음 [[a-curated-set-of-tools]]
+
+저희는 이러한 에이전트들의 역량을 강화할 수 있는 일련의 도구를 확인하고 있습니다.
+다음은 연동된 도구의 최신 목록입니다:
+
+- **문서 질문 답변**: 이미지 형식의 문서(예: PDF)가 주어지면 이 문서에 대한 질문에 답변합니다. ([Donut](./model_doc/donut))
+- **텍스트 질문 답변**: 긴 텍스트와 질문이 주어지면 텍스트에서 질문에 답변합니다. ([Flan-T5](./model_doc/flan-t5))
+- **무조건 이미지 캡셔닝**: 이미지에 캡션을 답니다! ([BLIP](./model_doc/blip))
+- **이미지 질문 답변**: 이미지가 주어지면 이 이미지에 대한 질문에 답변하기. ([VILT](./model_doc/vilt))
+- **이미지 분할**: 이미지와 프롬프트가 주어지면 해당 프롬프트의 분할 마스크를 출력합니다. ([CLIPSeg](./model_doc/clipseg))
+- **음성을 텍스트로 변환**: 사람이 말하는 오디오 녹음이 주어지면 음성을 텍스트로 변환합니다. ([Whisper](./model_doc/whisper))
+- **텍스트 음성 변환**: 텍스트를 음성으로 변환합니다. ([SpeechT5](./model_doc/speecht5))
+- **제로 샷(zero-shot) 텍스트 분류**: 텍스트와 레이블 목록이 주어지면 텍스트와 가장 관련 있는 레이블을 식별합니다. ([BART](./model_doc/bart))
+- **텍스트 요약**: 긴 텍스트를 한 문장 또는 몇 문장으로 요약합니다. ([BART](./model_doc/bart))
+- **번역**: 텍스트를 지정된 언어로 번역합니다. ([NLLB](./model_doc/nllb))
+
+이러한 도구는 트랜스포머에 통합되어 있으며, 예를 들어 수동으로도 사용할 수 있습니다:
+
+```py
+from transformers import load_tool
+
+tool = load_tool("text-to-speech")
+audio = tool("This is a text to speech tool")
+```
+
+### 사용자 정의 도구 [[custom-tools]]
+
+엄선된 도구 세트도 있지만, 이 구현이 제공하는 가장 큰 가치는 사용자 지정 도구를 빠르게 만들고 공유할 수 있다는 점입니다.
+
+도구의 코드를 Hugging Face Space나 모델 저장소에 푸시하면 에이전트에게 직접 도구를 활용할 수 있습니다. [`huggingface-tools` organization](https://huggingface.co/huggingface-tools)에 몇 가지 **트랜스포머에 구애받지 않는** 툴을 추가했습니다:
+
+- **텍스트 다운로더**: 웹 URL에서 텍스트를 다운로드합니다.
+- **텍스트 이미지 변환**: 프롬프트에 따라 이미지를 생성하여 안정적인 확산을 활용합니다.
+- **이미지 변환**: 초기 이미지와 프롬프트가 주어진 이미지를 수정하고, 안정적인 확산을 활용하는 지시 픽셀 2 픽셀을 활용합니다.
+- **텍스트 비디오 변환**: 프롬프트에 따라 작은 비디오를 생성하며, damo-vilab을 활용합니다.
+
+저희가 처음부터 사용하고 있는 텍스트-이미지 변환 도구는 [*huggingface-tools/text-to-image*](https://huggingface.co/spaces/huggingface-tools/text-to-image)에 있는 원격 도구입니다! 저희는 이 도구와 다른 조직에 이러한 도구를 계속 출시하여 이 구현을 더욱 강화할 것입니다.
+
+에이전트는 기본적으로 [`huggingface-tools`](https://huggingface.co/huggingface-tools)에 있는 도구에 접근할 수 있습니다.
+[다음 가이드](custom_tools)에서 도구를 작성하고 공유하는 방법과 Hub에 있는 사용자 지정 도구를 활용하는 방법에 대해 설명합니다.
+
+### 코드 생성[[code-generation]]
+
+지금까지 에이전트를 사용하여 작업을 수행하는 방법을 보여드렸습니다. 하지만 에이전트는 매우 제한된 Python 인터프리터를 사용하여 실행할 코드만 생성하고 있습니다. 다른 설정에서 생성된 코드를 사용하려는 경우 에이전트에게 도구 정의 및 정확한 가져오기와 함께 코드를 반환하라는 메시지를 표시할 수 있습니다.
+
+예를 들어 다음 명령어는
+```python
+agent.run("Draw me a picture of rivers and lakes", return_code=True)
+```
+
+다음 코드를 반환합니다.
+
+```python
+from transformers import load_tool
+
+image_generator = load_tool("huggingface-tools/text-to-image")
+
+image = image_generator(prompt="rivers and lakes")
+```
+
+이 코드는 직접 수정하고 실행할 수 있습니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/troubleshooting.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/troubleshooting.md
new file mode 100644
index 0000000000000000000000000000000000000000..263d693c23da65f7a964ee64fdde70dff595ad2c
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/troubleshooting.md
@@ -0,0 +1,198 @@
+
+
+# 문제 해결[[troubleshoot]]
+
+때때로 오류가 발생할 수 있지만, 저희가 도와드리겠습니다! 이 가이드는 현재까지 확인된 가장 일반적인 문제 몇 가지와 그것들을 해결하는 방법에 대해 다룹니다. 그러나 이 가이드는 모든 🤗 Transformers 문제를 포괄적으로 다루고 있지 않습니다. 문제 해결에 더 많은 도움을 받으려면 다음을 시도해보세요:
+
+
+
+1. [포럼](https://discuss.huggingface.co/)에서 도움을 요청하세요. [Beginners](https://discuss.huggingface.co/c/beginners/5) 또는 [🤗 Transformers](https://discuss.huggingface.co/c/transformers/9)와 같은 특정 카테고리에 질문을 게시할 수 있습니다. 재현 가능한 코드와 함께 잘 서술된 포럼 게시물을 작성하여 여러분의 문제가 해결될 가능성을 극대화하세요!
+
+
+
+2. 라이브러리와 관련된 버그이면 🤗 Transformers 저장소에서 [이슈](https://github.com/huggingface/transformers/issues/new/choose)를 생성하세요. 버그에 대해 설명하는 정보를 가능한 많이 포함하려고 노력하여, 무엇이 잘못 되었는지와 어떻게 수정할 수 있는지 더 잘 파악할 수 있도록 도와주세요.
+
+3. 이전 버전의 🤗 Transformers을 사용하는 경우 중요한 변경 사항이 버전 사이에 도입되었기 때문에 [마이그레이션](migration) 가이드를 확인하세요.
+
+문제 해결 및 도움 매뉴얼에 대한 자세한 내용은 Hugging Face 강좌의 [8장](https://huggingface.co/course/chapter8/1?fw=pt)을 참조하세요.
+
+
+## 방화벽 환경[[firewalled-environments]]
+
+클라우드 및 내부망(intranet) 설정의 일부 GPU 인스턴스는 외부 연결에 대한 방화벽으로 차단되어 연결 오류가 발생할 수 있습니다. 스크립트가 모델 가중치나 데이터를 다운로드하려고 할 때, 다운로드가 중단되고 다음 메시지와 함께 시간 초과됩니다:
+
+```
+ValueError: Connection error, and we cannot find the requested files in the cached path.
+Please try again or make sure your Internet connection is on.
+```
+
+이 경우에는 연결 오류를 피하기 위해 🤗 Transformers를 [오프라인 모드](installation#offline-mode)로 실행해야 합니다.
+
+## CUDA 메모리 부족(CUDA out of memory)[[cuda-out-of-memory]]
+
+수백만 개의 매개변수로 대규모 모델을 훈련하는 것은 적절한 하드웨어 없이 어려울 수 있습니다. GPU 메모리가 부족한 경우 발생할 수 있는 일반적인 오류는 다음과 같습니다:
+
+```
+CUDA out of memory. Tried to allocate 256.00 MiB (GPU 0; 11.17 GiB total capacity; 9.70 GiB already allocated; 179.81 MiB free; 9.85 GiB reserved in total by PyTorch)
+```
+
+다음은 메모리 사용을 줄이기 위해 시도해 볼 수 있는 몇 가지 잠재적인 해결책입니다:
+
+- [`TrainingArguments`]의 [`per_device_train_batch_size`](main_classes/trainer#transformers.TrainingArguments.per_device_train_batch_size) 값을 줄이세요.
+- [`TrainingArguments`]의 [`gradient_accumulation_steps`](main_classes/trainer#transformers.TrainingArguments.gradient_accumulation_steps)은 전체 배치 크기를 효과적으로 늘리세요.
+
+
+
+메모리 절약 기술에 대한 자세한 내용은 성능 [가이드](performance)를 참조하세요.
+
+
+
+## 저장된 TensorFlow 모델을 가져올 수 없습니다(Unable to load a saved TensorFlow model)[[unable-to-load-a-saved-uensorFlow-model]]
+
+TensorFlow의 [model.save](https://www.tensorflow.org/tutorials/keras/save_and_load#save_the_entire_model) 메소드는 아키텍처, 가중치, 훈련 구성 등 전체 모델을 단일 파일에 저장합니다. 그러나 모델 파일을 다시 가져올 때 🤗 Transformers는 모델 파일에 있는 모든 TensorFlow 관련 객체를 가져오지 않을 수 있기 때문에 오류가 발생할 수 있습니다. TensorFlow 모델 저장 및 가져오기 문제를 피하려면 다음을 권장합니다:
+
+- 모델 가중치를 `h5` 파일 확장자로 [`model.save_weights`](https://www.tensorflow.org/tutorials/keras/save_and_load#save_the_entire_model)로 저장한 다음 [`~TFPreTrainedModel.from_pretrained`]로 모델을 다시 가져옵니다:
+
+```py
+>>> from transformers import TFPreTrainedModel
+>>> from tensorflow import keras
+
+>>> model.save_weights("some_folder/tf_model.h5")
+>>> model = TFPreTrainedModel.from_pretrained("some_folder")
+```
+
+- 모델을 [`~TFPretrainedModel.save_pretrained`]로 저장하고 [`~TFPreTrainedModel.from_pretrained`]로 다시 가져옵니다:
+
+```py
+>>> from transformers import TFPreTrainedModel
+
+>>> model.save_pretrained("path_to/model")
+>>> model = TFPreTrainedModel.from_pretrained("path_to/model")
+```
+
+## ImportError[[importerror]]
+
+특히 최신 모델인 경우 만날 수 있는 다른 일반적인 오류는 `ImportError`입니다:
+
+```
+ImportError: cannot import name 'ImageGPTImageProcessor' from 'transformers' (unknown location)
+```
+
+이러한 오류 유형의 경우 최신 모델에 액세스할 수 있도록 최신 버전의 🤗 Transformers가 설치되어 있는지 확인하세요:
+
+```bash
+pip install transformers --upgrade
+```
+
+## CUDA error: device-side assert triggered[[cuda-error-deviceside-assert-triggered]]
+
+때때로 장치 코드 오류에 대한 일반적인 CUDA 오류가 발생할 수 있습니다.
+
+```
+RuntimeError: CUDA error: device-side assert triggered
+```
+
+더 자세한 오류 메시지를 얻으려면 우선 코드를 CPU에서 실행합니다. 다음 환경 변수를 코드의 시작 부분에 추가하여 CPU로 전환하세요:
+
+```py
+>>> import os
+
+>>> os.environ["CUDA_VISIBLE_DEVICES"] = ""
+```
+
+또 다른 옵션은 GPU에서 더 나은 역추적(traceback)을 얻는 것입니다. 다음 환경 변수를 코드의 시작 부분에 추가하여 역추적이 오류가 발생한 소스를 가리키도록 하세요:
+
+```py
+>>> import os
+
+>>> os.environ["CUDA_LAUNCH_BLOCKING"] = "1"
+```
+
+## 패딩 토큰이 마스킹되지 않은 경우 잘못된 출력(Incorrect output when padding tokens aren't masked)[[incorrect-output-when-padding-tokens-arent-masked]]
+
+경우에 따라 `input_ids`에 패딩 토큰이 포함된 경우 `hidden_state` 출력이 올바르지 않을 수 있습니다. 데모를 위해 모델과 토크나이저를 가져오세요. 모델의 `pad_token_id`에 액세스하여 해당 값을 확인할 수 있습니다. 일부 모델의 경우 `pad_token_id`가 `None`일 수 있지만 언제든지 수동으로 설정할 수 있습니다.
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+>>> import torch
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-uncased")
+>>> model.config.pad_token_id
+0
+```
+
+다음 예제는 패딩 토큰을 마스킹하지 않은 출력을 보여줍니다:
+
+```py
+>>> input_ids = torch.tensor([[7592, 2057, 2097, 2393, 9611, 2115], [7592, 0, 0, 0, 0, 0]])
+>>> output = model(input_ids)
+>>> print(output.logits)
+tensor([[ 0.0082, -0.2307],
+ [ 0.1317, -0.1683]], grad_fn=)
+```
+
+다음은 두 번째 시퀀스의 실제 출력입니다:
+
+```py
+>>> input_ids = torch.tensor([[7592]])
+>>> output = model(input_ids)
+>>> print(output.logits)
+tensor([[-0.1008, -0.4061]], grad_fn=)
+```
+
+대부분의 경우 모델에 `attention_mask`를 제공하여 패딩 토큰을 무시해야 이러한 조용한 오류를 방지할 수 있습니다. 이제 두 번째 시퀀스의 출력이 실제 출력과 일치합니다:
+
+
+
+일반적으로 토크나이저는 특정 토크나이저의 기본 값을 기준으로 사용자에 대한 'attention_mask'를 만듭니다.
+
+
+
+```py
+>>> attention_mask = torch.tensor([[1, 1, 1, 1, 1, 1], [1, 0, 0, 0, 0, 0]])
+>>> output = model(input_ids, attention_mask=attention_mask)
+>>> print(output.logits)
+tensor([[ 0.0082, -0.2307],
+ [-0.1008, -0.4061]], grad_fn=)
+```
+
+🤗 Transformers는 패딩 토큰이 제공된 경우 패딩 토큰을 마스킹하기 위한 `attention_mask`를 자동으로 생성하지 않습니다. 그 이유는 다음과 같습니다:
+
+- 일부 모델에는 패딩 토큰이 없습니다.
+- 일부 사용 사례의 경우 사용자가 모델이 패딩 토큰을 관리하기를 원합니다.
+
+## ValueError: 이 유형의 AutoModel에 대해 인식할 수 없는 XYZ 구성 클래스(ValueError: Unrecognized configuration class XYZ for this kind of AutoModel)[[valueerror-unrecognized-configuration-class-xyz-for-this-kind-of-automodel]]
+
+일반적으로, 사전 학습된 모델의 인스턴스를 가져오기 위해 [`AutoModel`] 클래스를 사용하는 것이 좋습니다.
+이 클래스는 구성에 따라 주어진 체크포인트에서 올바른 아키텍처를 자동으로 추론하고 가져올 수 있습니다.
+모델을 체크포인트에서 가져올 때 이 `ValueError`가 발생하면, 이는 Auto 클래스가 주어진 체크포인트의 구성에서
+가져오려는 모델 유형과 매핑을 찾을 수 없다는 것을 의미합니다. 가장 흔하게 발생하는 경우는
+체크포인트가 주어진 태스크를 지원하지 않을 때입니다.
+예를 들어, 다음 예제에서 질의응답에 대한 GPT2가 없기 때문에 오류가 발생합니다:
+
+```py
+>>> from transformers import AutoProcessor, AutoModelForQuestionAnswering
+
+>>> processor = AutoProcessor.from_pretrained("openai-community/gpt2-medium")
+>>> model = AutoModelForQuestionAnswering.from_pretrained("openai-community/gpt2-medium")
+ValueError: Unrecognized configuration class for this kind of AutoModel: AutoModelForQuestionAnswering.
+Model type should be one of AlbertConfig, BartConfig, BertConfig, BigBirdConfig, BigBirdPegasusConfig, BloomConfig, ...
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ms/_toctree.yml b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ms/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..e3fd6265b98d3ee39942c4d4a132771a3a709474
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ms/_toctree.yml
@@ -0,0 +1,684 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers
+ - local: quicktour
+ title: Lawatan cepat
+ - local: installation
+ title: Pemasangan
+ title: Mulakan
+- sections:
+ - local: pipeline_tutorial
+ title: Jalankan inferens dengan saluran paip
+ - local: autoclass_tutorial
+ title: Tulis kod mudah alih dengan AutoClass
+ - local: preprocessing
+ title: Praproses data
+ - local: training
+ title: Perhalusi model yang telah dilatih
+ - local: run_scripts
+ title: Latih dengan skrip
+ - local: accelerate
+ title: Sediakan latihan yang diedarkan dengan 🤗 Accelerate
+ - local: model_sharing
+ title: Kongsi model anda
+ - local: transformers_agents
+ title: Ejen
+ title: Tutorials
+- sections:
+ - sections:
+ - local: tasks/sequence_classification
+ title: Klasifikasi teks
+ - local: tasks/token_classification
+ title: Klasifikasi token
+ - local: tasks/question_answering
+ title: Soalan menjawab
+ - local: tasks/language_modeling
+ title: Pemodelan bahasa sebab-akibat
+ - local: tasks/masked_language_modeling
+ title: Pemodelan bahasa Masked
+ - local: tasks/translation
+ title: Terjemahan
+ - local: tasks/summarization
+ title: Rumusan
+ - local: tasks/multiple_choice
+ title: Pilihan
+ title: Natural Language Processing
+ isExpanded: false
+ - sections:
+ - local: tasks/audio_classification
+ title: Klasifikasi audio
+ - local: tasks/asr
+ title: Pengecaman pertuturan automatik
+ title: Audio
+ isExpanded: false
+ - sections:
+ - local: tasks/image_classification
+ title: Klasifikasi imej
+ - local: tasks/semantic_segmentation
+ title: Segmentasi semantik
+ - local: tasks/video_classification
+ title: Klasifikasi video
+ - local: tasks/object_detection
+ title: Pengesanan objek
+ - local: tasks/zero_shot_object_detection
+ title: Pengesanan objek Zero-Shot
+ - local: tasks/zero_shot_image_classification
+ title: Klasifikasi imej tangkapan Zero-Shot
+ - local: tasks/monocular_depth_estimation
+ title: Anggaran kedalaman
+ title: Visi komputer
+ isExpanded: false
+ - sections:
+ - local: tasks/image_captioning
+ title: Kapsyen imej
+ - local: tasks/document_question_answering
+ title: Menjawab Soalan Dokumen
+ - local: tasks/text-to-speech
+ title: Teks kepada ucapan
+ title: Multimodal
+ isExpanded: false
+ title: Panduan Tugasan
+- sections:
+ - local: fast_tokenizers
+ title: Gunakan tokenizer cepat dari 🤗 Tokenizers
+ - local: multilingual
+ title: Jalankan inferens dengan model berbilang bahasa
+ - local: generation_strategies
+ title: Sesuaikan strategi penjanaan teks
+ - local: create_a_model
+ title: Gunakan API khusus model
+ - local: custom_models
+ title: Kongsi model tersuai
+ - local: sagemaker
+ title: Jalankan latihan di Amazon SageMaker
+ - local: serialization
+ title: Eksport ke ONNX
+ - local: torchscript
+ title: Eksport ke TorchScript
+ - local: Buku nota dengan contoh
+ title: Notebooks with examples
+ - local: Sumber komuniti
+ title: Community resources
+ - local: Sumber komuniti
+ title: Custom Tools and Prompts
+ - local: Alat dan Gesaan Tersuai
+ title: Selesaikan masalah
+ title: Panduan Developer
+- sections:
+ - local: performance
+ title: Gambaran keseluruhan
+ - local: perf_train_gpu_one
+ title: Latihan pada satu GPU
+ - local: perf_train_gpu_many
+ title: Latihan pada banyak GPU
+ - local: perf_train_cpu
+ title: Latihan mengenai CPU
+ - local: perf_train_cpu_many
+ title: Latihan pada banyak CPU
+ - local: perf_train_tpu
+ title: Latihan mengenai TPU
+ - local: perf_train_tpu_tf
+ title: Latihan tentang TPU dengan TensorFlow
+ - local: perf_train_special
+ title: Latihan mengenai Perkakasan Khusus
+ - local: perf_infer_cpu
+ title: Inferens pada CPU
+ - local: perf_infer_gpu_one
+ title: Inferens pada satu GPU
+ - local: perf_infer_gpu_many
+ title: Inferens pada banyak GPUs
+ - local: perf_infer_special
+ title: Inferens pada Perkakasan Khusus
+ - local: perf_hardware
+ title: Perkakasan tersuai untuk latihan
+ - local: big_models
+ title: Menghidupkan model besar
+ - local: debugging
+ title: Penyahpepijatan
+ - local: hpo_train
+ title: Carian Hiperparameter menggunakan API Pelatih
+ - local: tf_xla
+ title: Penyepaduan XLA untuk Model TensorFlow
+ title: Prestasi dan kebolehskalaan
+- sections:
+ - local: contributing
+ title: Bagaimana untuk menyumbang kepada transformer?
+ - local: add_new_model
+ title: Bagaimana untuk menambah model pada 🤗 Transformers?
+ - local: add_new_pipeline
+ title: Bagaimana untuk menambah saluran paip ke 🤗 Transformers?
+ - local: testing
+ title: Ujian
+ - local: pr_checks
+ title: Menyemak Permintaan Tarik
+ title: Sumbangkan
+
+- sections:
+ - local: philosophy
+ title: Falsafah
+ - local: glossary
+ title: Glosari
+ - local: task_summary
+ title: Apa 🤗 Transformers boleh buat
+ - local: tasks_explained
+ title: Bagaimana 🤗 Transformers menyelesaikan tugasan
+ - local: model_summary
+ title: Keluarga model Transformer
+ - local: tokenizer_summary
+ title: Ringkasan tokenizer
+ - local: attention
+ title: Mekanisme perhatian
+ - local: pad_truncation
+ title: Padding dan pemotongan
+ - local: bertology
+ title: BERTology
+ - local: perplexity
+ title: Kekeliruan model panjang tetap
+ - local: pipeline_webserver
+ title: Saluran paip untuk inferens pelayan web
+ title: Panduan konsep
+- sections:
+ - sections:
+ - local: main_classes/agent
+ title: Ejen dan Alat
+ - local: model_doc/auto
+ title: Kelas Auto
+ - local: main_classes/callback
+ title: Panggilan balik
+ - local: main_classes/configuration
+ title: Configuration
+ - local: main_classes/data_collator
+ title: Data Collator
+ - local: main_classes/keras_callbacks
+ title: Keras callbacks
+ - local: main_classes/logging
+ title: Logging
+ - local: main_classes/model
+ title: Models
+ - local: main_classes/text_generation
+ title: Text Generation
+ - local: main_classes/onnx
+ title: ONNX
+ - local: main_classes/optimizer_schedules
+ title: Optimization
+ - local: main_classes/output
+ title: Model outputs
+ - local: main_classes/pipelines
+ title: Pipelines
+ - local: main_classes/processors
+ title: Processors
+ - local: main_classes/quantization
+ title: Quantization
+ - local: main_classes/tokenizer
+ title: Tokenizer
+ - local: main_classes/trainer
+ title: Trainer
+ - local: main_classes/deepspeed
+ title: DeepSpeed Integration
+ - local: main_classes/feature_extractor
+ title: Feature Extractor
+ - local: main_classes/image_processor
+ title: Image Processor
+ title: Main Classes
+ - sections:
+ - isExpanded: false
+ sections:
+ - local: model_doc/albert
+ title: ALBERT
+ - local: model_doc/bart
+ title: BART
+ - local: model_doc/barthez
+ title: BARThez
+ - local: model_doc/bartpho
+ title: BARTpho
+ - local: model_doc/bert
+ title: BERT
+ - local: model_doc/bert-generation
+ title: BertGeneration
+ - local: model_doc/bert-japanese
+ title: BertJapanese
+ - local: model_doc/bertweet
+ title: Bertweet
+ - local: model_doc/big_bird
+ title: BigBird
+ - local: model_doc/bigbird_pegasus
+ title: BigBirdPegasus
+ - local: model_doc/biogpt
+ title: BioGpt
+ - local: model_doc/blenderbot
+ title: Blenderbot
+ - local: model_doc/blenderbot-small
+ title: Blenderbot Small
+ - local: model_doc/bloom
+ title: BLOOM
+ - local: model_doc/bort
+ title: BORT
+ - local: model_doc/byt5
+ title: ByT5
+ - local: model_doc/camembert
+ title: CamemBERT
+ - local: model_doc/canine
+ title: CANINE
+ - local: model_doc/codegen
+ title: CodeGen
+ - local: model_doc/convbert
+ title: ConvBERT
+ - local: model_doc/cpm
+ title: CPM
+ - local: model_doc/cpmant
+ title: CPMANT
+ - local: model_doc/ctrl
+ title: CTRL
+ - local: model_doc/deberta
+ title: DeBERTa
+ - local: model_doc/deberta-v2
+ title: DeBERTa-v2
+ - local: model_doc/dialogpt
+ title: DialoGPT
+ - local: model_doc/distilbert
+ title: DistilBERT
+ - local: model_doc/dpr
+ title: DPR
+ - local: model_doc/electra
+ title: ELECTRA
+ - local: model_doc/encoder-decoder
+ title: Encoder Decoder Models
+ - local: model_doc/ernie
+ title: ERNIE
+ - local: model_doc/ernie_m
+ title: ErnieM
+ - local: model_doc/esm
+ title: ESM
+ - local: model_doc/flan-t5
+ title: FLAN-T5
+ - local: model_doc/flan-ul2
+ title: FLAN-UL2
+ - local: model_doc/flaubert
+ title: FlauBERT
+ - local: model_doc/fnet
+ title: FNet
+ - local: model_doc/fsmt
+ title: FSMT
+ - local: model_doc/funnel
+ title: Funnel Transformer
+ - local: model_doc/openai-gpt
+ title: GPT
+ - local: model_doc/gpt_neo
+ title: GPT Neo
+ - local: model_doc/gpt_neox
+ title: GPT NeoX
+ - local: model_doc/gpt_neox_japanese
+ title: GPT NeoX Japanese
+ - local: model_doc/gptj
+ title: GPT-J
+ - local: model_doc/gpt2
+ title: GPT2
+ - local: model_doc/gpt_bigcode
+ title: GPTBigCode
+ - local: model_doc/gptsan-japanese
+ title: GPTSAN Japanese
+ - local: model_doc/gpt-sw3
+ title: GPTSw3
+ - local: model_doc/herbert
+ title: HerBERT
+ - local: model_doc/ibert
+ title: I-BERT
+ - local: model_doc/jukebox
+ title: Jukebox
+ - local: model_doc/led
+ title: LED
+ - local: model_doc/llama
+ title: LLaMA
+ - local: model_doc/longformer
+ title: Longformer
+ - local: model_doc/longt5
+ title: LongT5
+ - local: model_doc/luke
+ title: LUKE
+ - local: model_doc/m2m_100
+ title: M2M100
+ - local: model_doc/marian
+ title: MarianMT
+ - local: model_doc/markuplm
+ title: MarkupLM
+ - local: model_doc/mbart
+ title: MBart and MBart-50
+ - local: model_doc/mega
+ title: MEGA
+ - local: model_doc/megatron-bert
+ title: MegatronBERT
+ - local: model_doc/megatron_gpt2
+ title: MegatronGPT2
+ - local: model_doc/mluke
+ title: mLUKE
+ - local: model_doc/mobilebert
+ title: MobileBERT
+ - local: model_doc/mpnet
+ title: MPNet
+ - local: model_doc/mt5
+ title: MT5
+ - local: model_doc/mvp
+ title: MVP
+ - local: model_doc/nezha
+ title: NEZHA
+ - local: model_doc/nllb
+ title: NLLB
+ - local: model_doc/nllb-moe
+ title: NLLB-MoE
+ - local: model_doc/nystromformer
+ title: Nyströmformer
+ - local: model_doc/open-llama
+ title: Open-Llama
+ - local: model_doc/opt
+ title: OPT
+ - local: model_doc/pegasus
+ title: Pegasus
+ - local: model_doc/pegasus_x
+ title: PEGASUS-X
+ - local: model_doc/phobert
+ title: PhoBERT
+ - local: model_doc/plbart
+ title: PLBart
+ - local: model_doc/prophetnet
+ title: ProphetNet
+ - local: model_doc/qdqbert
+ title: QDQBert
+ - local: model_doc/rag
+ title: RAG
+ - local: model_doc/realm
+ title: REALM
+ - local: model_doc/reformer
+ title: Reformer
+ - local: model_doc/rembert
+ title: RemBERT
+ - local: model_doc/retribert
+ title: RetriBERT
+ - local: model_doc/roberta
+ title: RoBERTa
+ - local: model_doc/roberta-prelayernorm
+ title: RoBERTa-PreLayerNorm
+ - local: model_doc/roc_bert
+ title: RoCBert
+ - local: model_doc/roformer
+ title: RoFormer
+ - local: model_doc/rwkv
+ title: RWKV
+ - local: model_doc/splinter
+ title: Splinter
+ - local: model_doc/squeezebert
+ title: SqueezeBERT
+ - local: model_doc/switch_transformers
+ title: SwitchTransformers
+ - local: model_doc/t5
+ title: T5
+ - local: model_doc/t5v1.1
+ title: T5v1.1
+ - local: model_doc/tapex
+ title: TAPEX
+ - local: model_doc/transfo-xl
+ title: Transformer XL
+ - local: model_doc/ul2
+ title: UL2
+ - local: model_doc/xmod
+ title: X-MOD
+ - local: model_doc/xglm
+ title: XGLM
+ - local: model_doc/xlm
+ title: XLM
+ - local: model_doc/xlm-prophetnet
+ title: XLM-ProphetNet
+ - local: model_doc/xlm-roberta
+ title: XLM-RoBERTa
+ - local: model_doc/xlm-roberta-xl
+ title: XLM-RoBERTa-XL
+ - local: model_doc/xlm-v
+ title: XLM-V
+ - local: model_doc/xlnet
+ title: XLNet
+ - local: model_doc/yoso
+ title: YOSO
+ title: Text models
+ - isExpanded: false
+ sections:
+ - local: model_doc/beit
+ title: BEiT
+ - local: model_doc/bit
+ title: BiT
+ - local: model_doc/conditional_detr
+ title: Conditional DETR
+ - local: model_doc/convnext
+ title: ConvNeXT
+ - local: model_doc/convnextv2
+ title: ConvNeXTV2
+ - local: model_doc/cvt
+ title: CvT
+ - local: model_doc/deformable_detr
+ title: Deformable DETR
+ - local: model_doc/deit
+ title: DeiT
+ - local: model_doc/deta
+ title: DETA
+ - local: model_doc/detr
+ title: DETR
+ - local: model_doc/dinat
+ title: DiNAT
+ - local: model_doc/dit
+ title: DiT
+ - local: model_doc/dpt
+ title: DPT
+ - local: model_doc/efficientformer
+ title: EfficientFormer
+ - local: model_doc/efficientnet
+ title: EfficientNet
+ - local: model_doc/focalnet
+ title: FocalNet
+ - local: model_doc/glpn
+ title: GLPN
+ - local: model_doc/imagegpt
+ title: ImageGPT
+ - local: model_doc/levit
+ title: LeViT
+ - local: model_doc/mask2former
+ title: Mask2Former
+ - local: model_doc/maskformer
+ title: MaskFormer
+ - local: model_doc/mobilenet_v1
+ title: MobileNetV1
+ - local: model_doc/mobilenet_v2
+ title: MobileNetV2
+ - local: model_doc/mobilevit
+ title: MobileViT
+ - local: model_doc/nat
+ title: NAT
+ - local: model_doc/poolformer
+ title: PoolFormer
+ - local: model_doc/regnet
+ title: RegNet
+ - local: model_doc/resnet
+ title: ResNet
+ - local: model_doc/segformer
+ title: SegFormer
+ - local: model_doc/swiftformer
+ title: SwiftFormer
+ - local: model_doc/swin
+ title: Swin Transformer
+ - local: model_doc/swinv2
+ title: Swin Transformer V2
+ - local: model_doc/swin2sr
+ title: Swin2SR
+ - local: model_doc/table-transformer
+ title: Table Transformer
+ - local: model_doc/timesformer
+ title: TimeSformer
+ - local: model_doc/upernet
+ title: UperNet
+ - local: model_doc/van
+ title: VAN
+ - local: model_doc/videomae
+ title: VideoMAE
+ - local: model_doc/vit
+ title: Vision Transformer (ViT)
+ - local: model_doc/vit_hybrid
+ title: ViT Hybrid
+ - local: model_doc/vit_mae
+ title: ViTMAE
+ - local: model_doc/vit_msn
+ title: ViTMSN
+ - local: model_doc/yolos
+ title: YOLOS
+ title: Vision models
+ - isExpanded: false
+ sections:
+ - local: model_doc/audio-spectrogram-transformer
+ title: Audio Spectrogram Transformer
+ - local: model_doc/clap
+ title: CLAP
+ - local: model_doc/hubert
+ title: Hubert
+ - local: model_doc/mctct
+ title: MCTCT
+ - local: model_doc/sew
+ title: SEW
+ - local: model_doc/sew-d
+ title: SEW-D
+ - local: model_doc/speech_to_text
+ title: Speech2Text
+ - local: model_doc/speech_to_text_2
+ title: Speech2Text2
+ - local: model_doc/speecht5
+ title: SpeechT5
+ - local: model_doc/unispeech
+ title: UniSpeech
+ - local: model_doc/unispeech-sat
+ title: UniSpeech-SAT
+ - local: model_doc/wav2vec2
+ title: Wav2Vec2
+ - local: model_doc/wav2vec2-conformer
+ title: Wav2Vec2-Conformer
+ - local: model_doc/wav2vec2_phoneme
+ title: Wav2Vec2Phoneme
+ - local: model_doc/wavlm
+ title: WavLM
+ - local: model_doc/whisper
+ title: Whisper
+ - local: model_doc/xls_r
+ title: XLS-R
+ - local: model_doc/xlsr_wav2vec2
+ title: XLSR-Wav2Vec2
+ title: Audio models
+ - isExpanded: false
+ sections:
+ - local: model_doc/align
+ title: ALIGN
+ - local: model_doc/altclip
+ title: AltCLIP
+ - local: model_doc/blip
+ title: BLIP
+ - local: model_doc/blip-2
+ title: BLIP-2
+ - local: model_doc/bridgetower
+ title: BridgeTower
+ - local: model_doc/chinese_clip
+ title: Chinese-CLIP
+ - local: model_doc/clip
+ title: CLIP
+ - local: model_doc/clipseg
+ title: CLIPSeg
+ - local: model_doc/data2vec
+ title: Data2Vec
+ - local: model_doc/deplot
+ title: DePlot
+ - local: model_doc/donut
+ title: Donut
+ - local: model_doc/flava
+ title: FLAVA
+ - local: model_doc/git
+ title: GIT
+ - local: model_doc/groupvit
+ title: GroupViT
+ - local: model_doc/layoutlm
+ title: LayoutLM
+ - local: model_doc/layoutlmv2
+ title: LayoutLMV2
+ - local: model_doc/layoutlmv3
+ title: LayoutLMV3
+ - local: model_doc/layoutxlm
+ title: LayoutXLM
+ - local: model_doc/lilt
+ title: LiLT
+ - local: model_doc/lxmert
+ title: LXMERT
+ - local: model_doc/matcha
+ title: MatCha
+ - local: model_doc/mgp-str
+ title: MGP-STR
+ - local: model_doc/oneformer
+ title: OneFormer
+ - local: model_doc/owlvit
+ title: OWL-ViT
+ - local: model_doc/perceiver
+ title: Perceiver
+ - local: model_doc/pix2struct
+ title: Pix2Struct
+ - local: model_doc/sam
+ title: Segment Anything
+ - local: model_doc/speech-encoder-decoder
+ title: Speech Encoder Decoder Models
+ - local: model_doc/tapas
+ title: TAPAS
+ - local: model_doc/trocr
+ title: TrOCR
+ - local: model_doc/tvlt
+ title: TVLT
+ - local: model_doc/vilt
+ title: ViLT
+ - local: model_doc/vision-encoder-decoder
+ title: Vision Encoder Decoder Models
+ - local: model_doc/vision-text-dual-encoder
+ title: Vision Text Dual Encoder
+ - local: model_doc/visual_bert
+ title: VisualBERT
+ - local: model_doc/xclip
+ title: X-CLIP
+ title: Multimodal models
+ - isExpanded: false
+ sections:
+ - local: model_doc/decision_transformer
+ title: Decision Transformer
+ - local: model_doc/trajectory_transformer
+ title: Trajectory Transformer
+ title: Reinforcement learning models
+ - isExpanded: false
+ sections:
+ - local: model_doc/informer
+ title: Informer
+ - local: model_doc/time_series_transformer
+ title: Time Series Transformer
+ title: Time series models
+ - isExpanded: false
+ sections:
+ - local: model_doc/graphormer
+ title: Graphormer
+ title: Graph models
+ title: Models
+ - sections:
+ - local: internal/modeling_utils
+ title: Custom Layers and Utilities
+ - local: internal/pipelines_utils
+ title: Utilities for pipelines
+ - local: internal/tokenization_utils
+ title: Utilities for Tokenizers
+ - local: internal/trainer_utils
+ title: Utilities for Trainer
+ - local: internal/generation_utils
+ title: Utilities for Generation
+ - local: internal/image_processing_utils
+ title: Utilities for Image Processors
+ - local: internal/audio_utils
+ title: Utilities for Audio processing
+ - local: internal/file_utils
+ title: General Utilities
+ - local: internal/time_series_utils
+ title: Utilities for Time Series
+ title: Internal Helpers
+ title: API
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ms/index.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ms/index.md
new file mode 100644
index 0000000000000000000000000000000000000000..f51c43c9bd01a63f3303e4a2306449bdc31b75f9
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ms/index.md
@@ -0,0 +1,464 @@
+
+
+# 🤗 Transformers
+
+Pembelajaran Mesin terkini untuk [PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/), dan [JAX](https://jax.readthedocs.io/en/latest/).
+
+🤗 Transformers menyediakan API dan alatan untuk memuat turun dan melatih model pra-latihan terkini dengan mudah. Menggunakan model terlatih boleh mengurangkan kos pengiraan anda, jejak karbon dan menjimatkan masa serta sumber yang diperlukan untuk melatih model dari awal. Model ini menyokong tugas biasa dalam modaliti yang berbeza, seperti:
+
+📝 **Natural Language Processing**: klasifikasi teks, pengecaman entiti bernama, menjawab soalan, pemodelan bahasa, ringkasan, terjemahan, pilihan berganda dan penjanaan teks.
+🖼️ **Computer Vision**: pengelasan imej, pengesanan objek dan pembahagian.
+🗣️ **Audio**: pengecaman pertuturan automatik dan klasifikasi audio.
+🐙 **Multimodal**: jawapan soalan jadual, pengecaman aksara optik, pengekstrakan maklumat daripada dokumen yang diimbas, klasifikasi video dan jawapan soalan visual.
+
+🤗 Transformer menyokong kebolehoperasian rangka kerja antara PyTorch, TensorFlow, and JAX. Ini memberikan fleksibiliti untuk menggunakan rangka kerja yang berbeza pada setiap peringkat kehidupan model; latih model dalam tiga baris kod dalam satu rangka kerja, dan muatkannya untuk inferens dalam rangka kerja yang lain. Model juga boleh dieksport ke format seperti ONNX.
+
+Sertai komuniti yang semakin berkembang di [Hub](https://huggingface.co/models), [forum](https://discuss.huggingface.co/), atau [Discord](https://discord.com/invite/JfAtkvEtRb) hari ini!
+
+## Jika anda sedang mencari sokongan tersuai daripada pasukan Hugging Face
+
+
+
+
+
+## Kandungan
+
+Dokumentasi disusun kepada lima bahagian:
+
+- **MULAKAN** menyediakan lawatan pantas ke perpustakaan dan arahan pemasangan untuk bangun dan berjalan.
+- **TUTORIAL** ialah tempat yang bagus untuk bermula jika anda seorang pemula. Bahagian ini akan membantu anda memperoleh kemahiran asas yang anda perlukan untuk mula menggunakan perpustakaan.
+- **PANDUAN CARA-CARA** menunjukkan kepada anda cara untuk mencapai matlamat tertentu, seperti memperhalusi model terlatih untuk pemodelan bahasa atau cara menulis dan berkongsi model tersuai.
+- **PANDUAN KONSEP** menawarkan lebih banyak perbincangan dan penjelasan tentang konsep dan idea asas di sebalik model, tugasan dan falsafah reka bentuk 🤗 Transformers.
+- **API** menerangkan semua kelas dan fungsi:
+
+ - **KELAS UTAMA** memperincikan kelas yang paling penting seperti konfigurasi, model, tokenizer dan saluran paip.
+ - **MODEL** memperincikan kelas dan fungsi yang berkaitan dengan setiap model yang dilaksanakan dalam perpustakaan.
+ - **PEMBANTU DALAMAN** memperincikan kelas utiliti dan fungsi yang digunakan secara dalaman.
+
+### Model yang disokong
+
+
+
+1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
+1. **[ALIGN](model_doc/align)** (from Google Research) released with the paper [Scaling Up Visual and Vision-Language Representation Learning With Noisy Text Supervision](https://arxiv.org/abs/2102.05918) by Chao Jia, Yinfei Yang, Ye Xia, Yi-Ting Chen, Zarana Parekh, Hieu Pham, Quoc V. Le, Yunhsuan Sung, Zhen Li, Tom Duerig.
+1. **[AltCLIP](model_doc/altclip)** (from BAAI) released with the paper [AltCLIP: Altering the Language Encoder in CLIP for Extended Language Capabilities](https://arxiv.org/abs/2211.06679) by Chen, Zhongzhi and Liu, Guang and Zhang, Bo-Wen and Ye, Fulong and Yang, Qinghong and Wu, Ledell.
+1. **[Audio Spectrogram Transformer](model_doc/audio-spectrogram-transformer)** (from MIT) released with the paper [AST: Audio Spectrogram Transformer](https://arxiv.org/abs/2104.01778) by Yuan Gong, Yu-An Chung, James Glass.
+1. **[Autoformer](model_doc/autoformer)** (from Tsinghua University) released with the paper [Autoformer: Decomposition Transformers with Auto-Correlation for Long-Term Series Forecasting](https://arxiv.org/abs/2106.13008) by Haixu Wu, Jiehui Xu, Jianmin Wang, Mingsheng Long.
+1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
+1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
+1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
+1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
+1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
+1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
+1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BioGpt](model_doc/biogpt)** (from Microsoft Research AI4Science) released with the paper [BioGPT: generative pre-trained transformer for biomedical text generation and mining](https://academic.oup.com/bib/advance-article/doi/10.1093/bib/bbac409/6713511?guestAccessKey=a66d9b5d-4f83-4017-bb52-405815c907b9) by Renqian Luo, Liai Sun, Yingce Xia, Tao Qin, Sheng Zhang, Hoifung Poon and Tie-Yan Liu.
+1. **[BiT](model_doc/bit)** (from Google AI) released with the paper [Big Transfer (BiT): General Visual Representation Learning](https://arxiv.org/abs/1912.11370) by Alexander Kolesnikov, Lucas Beyer, Xiaohua Zhai, Joan Puigcerver, Jessica Yung, Sylvain Gelly, Neil Houlsby.
+1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BLIP](model_doc/blip)** (from Salesforce) released with the paper [BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation](https://arxiv.org/abs/2201.12086) by Junnan Li, Dongxu Li, Caiming Xiong, Steven Hoi.
+1. **[BLIP-2](model_doc/blip-2)** (from Salesforce) released with the paper [BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models](https://arxiv.org/abs/2301.12597) by Junnan Li, Dongxu Li, Silvio Savarese, Steven Hoi.
+1. **[BLOOM](model_doc/bloom)** (from BigScience workshop) released by the [BigScience Workshop](https://bigscience.huggingface.co/).
+1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499) by Adrian de Wynter and Daniel J. Perry.
+1. **[BridgeTower](model_doc/bridgetower)** (from Harbin Institute of Technology/Microsoft Research Asia/Intel Labs) released with the paper [BridgeTower: Building Bridges Between Encoders in Vision-Language Representation Learning](https://arxiv.org/abs/2206.08657) by Xiao Xu, Chenfei Wu, Shachar Rosenman, Vasudev Lal, Wanxiang Che, Nan Duan.
+1. **[Bros](model_doc/bros)** (from NAVER) released with the paper [BROS: A Pre-trained Language Model Focusing on Text and Layout for Better Key Information Extraction from Documents](https://arxiv.org/abs/2108.04539) by Teakgyu Hong, Donghyun Kim, Mingi Ji, Wonseok Hwang, Daehyun Nam, Sungrae Park.
+1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
+1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
+1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
+1. **[Chinese-CLIP](model_doc/chinese_clip)** (from OFA-Sys) released with the paper [Chinese CLIP: Contrastive Vision-Language Pretraining in Chinese](https://arxiv.org/abs/2211.01335) by An Yang, Junshu Pan, Junyang Lin, Rui Men, Yichang Zhang, Jingren Zhou, Chang Zhou.
+1. **[CLAP](model_doc/clap)** (from LAION-AI) released with the paper [Large-scale Contrastive Language-Audio Pretraining with Feature Fusion and Keyword-to-Caption Augmentation](https://arxiv.org/abs/2211.06687) by Yusong Wu, Ke Chen, Tianyu Zhang, Yuchen Hui, Taylor Berg-Kirkpatrick, Shlomo Dubnov.
+1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
+1. **[CLIPSeg](model_doc/clipseg)** (from University of Göttingen) released with the paper [Image Segmentation Using Text and Image Prompts](https://arxiv.org/abs/2112.10003) by Timo Lüddecke and Alexander Ecker.
+1. **[CodeGen](model_doc/codegen)** (from Salesforce) released with the paper [A Conversational Paradigm for Program Synthesis](https://arxiv.org/abs/2203.13474) by Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Savarese, Caiming Xiong.
+1. **[Conditional DETR](model_doc/conditional_detr)** (from Microsoft Research Asia) released with the paper [Conditional DETR for Fast Training Convergence](https://arxiv.org/abs/2108.06152) by Depu Meng, Xiaokang Chen, Zejia Fan, Gang Zeng, Houqiang Li, Yuhui Yuan, Lei Sun, Jingdong Wang.
+1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
+1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+1. **[CPM-Ant](model_doc/cpmant)** (from OpenBMB) released by the [OpenBMB](https://www.openbmb.org/).
+1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
+1. **[CvT](model_doc/cvt)** (from Microsoft) released with the paper [CvT: Introducing Convolutions to Vision Transformers](https://arxiv.org/abs/2103.15808) by Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang.
+1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
+1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+1. **[Deformable DETR](model_doc/deformable_detr)** (from SenseTime Research) released with the paper [Deformable DETR: Deformable Transformers for End-to-End Object Detection](https://arxiv.org/abs/2010.04159) by Xizhou Zhu, Weijie Su, Lewei Lu, Bin Li, Xiaogang Wang, Jifeng Dai.
+1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
+1. **[DePlot](model_doc/deplot)** (from Google AI) released with the paper [DePlot: One-shot visual language reasoning by plot-to-table translation](https://arxiv.org/abs/2212.10505) by Fangyu Liu, Julian Martin Eisenschlos, Francesco Piccinno, Syrine Krichene, Chenxi Pang, Kenton Lee, Mandar Joshi, Wenhu Chen, Nigel Collier, Yasemin Altun.
+1. **[DETA](model_doc/deta)** (from The University of Texas at Austin) released with the paper [NMS Strikes Back](https://arxiv.org/abs/2212.06137) by Jeffrey Ouyang-Zhang, Jang Hyun Cho, Xingyi Zhou, Philipp Krähenbühl.
+1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
+1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
+1. **[DiNAT](model_doc/dinat)** (from SHI Labs) released with the paper [Dilated Neighborhood Attention Transformer](https://arxiv.org/abs/2209.15001) by Ali Hassani and Humphrey Shi.
+1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) and a German version of DistilBERT.
+1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
+1. **[Donut](model_doc/donut)** (from NAVER), released together with the paper [OCR-free Document Understanding Transformer](https://arxiv.org/abs/2111.15664) by Geewook Kim, Teakgyu Hong, Moonbin Yim, Jeongyeon Nam, Jinyoung Park, Jinyeong Yim, Wonseok Hwang, Sangdoo Yun, Dongyoon Han, Seunghyun Park.
+1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
+1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+1. **[EfficientFormer](model_doc/efficientformer)** (from Snap Research) released with the paper [EfficientFormer: Vision Transformers at MobileNetSpeed](https://arxiv.org/abs/2206.01191) by Yanyu Li, Geng Yuan, Yang Wen, Ju Hu, Georgios Evangelidis, Sergey Tulyakov, Yanzhi Wang, Jian Ren.
+1. **[EfficientNet](model_doc/efficientnet)** (from Google Brain) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://arxiv.org/abs/1905.11946) by Mingxing Tan, Quoc V. Le.
+1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
+1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[ERNIE](model_doc/ernie)** (from Baidu) released with the paper [ERNIE: Enhanced Representation through Knowledge Integration](https://arxiv.org/abs/1904.09223) by Yu Sun, Shuohuan Wang, Yukun Li, Shikun Feng, Xuyi Chen, Han Zhang, Xin Tian, Danxiang Zhu, Hao Tian, Hua Wu.
+1. **[ErnieM](model_doc/ernie_m)** (from Baidu) released with the paper [ERNIE-M: Enhanced Multilingual Representation by Aligning Cross-lingual Semantics with Monolingual Corpora](https://arxiv.org/abs/2012.15674) by Xuan Ouyang, Shuohuan Wang, Chao Pang, Yu Sun, Hao Tian, Hua Wu, Haifeng Wang.
+1. **[ESM](model_doc/esm)** (from Meta AI) are transformer protein language models. **ESM-1b** was released with the paper [Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118) by Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott, C. Lawrence Zitnick, Jerry Ma, and Rob Fergus. **ESM-1v** was released with the paper [Language models enable zero-shot prediction of the effects of mutations on protein function](https://doi.org/10.1101/2021.07.09.450648) by Joshua Meier, Roshan Rao, Robert Verkuil, Jason Liu, Tom Sercu and Alexander Rives. **ESM-2 and ESMFold** were released with the paper [Language models of protein sequences at the scale of evolution enable accurate structure prediction](https://doi.org/10.1101/2022.07.20.500902) by Zeming Lin, Halil Akin, Roshan Rao, Brian Hie, Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido, Alexander Rives.
+1. **[FLAN-T5](model_doc/flan-t5)** (from Google AI) released in the repository [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-t5-checkpoints) by Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V. Le, and Jason Wei
+1. **[FLAN-UL2](model_doc/flan-ul2)** (from Google AI) released in the repository [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-ul2-checkpoints) by Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V. Le, and Jason Wei
+1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
+1. **[FLAVA](model_doc/flava)** (from Facebook AI) released with the paper [FLAVA: A Foundational Language And Vision Alignment Model](https://arxiv.org/abs/2112.04482) by Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela.
+1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
+1. **[FocalNet](model_doc/focalnet)** (from Microsoft Research) released with the paper [Focal Modulation Networks](https://arxiv.org/abs/2203.11926) by Jianwei Yang, Chunyuan Li, Xiyang Dai, Lu Yuan, Jianfeng Gao.
+1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
+1. **[GIT](model_doc/git)** (from Microsoft Research) released with the paper [GIT: A Generative Image-to-text Transformer for Vision and Language](https://arxiv.org/abs/2205.14100) by Jianfeng Wang, Zhengyuan Yang, Xiaowei Hu, Linjie Li, Kevin Lin, Zhe Gan, Zicheng Liu, Ce Liu, Lijuan Wang.
+1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
+1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
+1. **[GPT NeoX](model_doc/gpt_neox)** (from EleutherAI) released with the paper [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://arxiv.org/abs/2204.06745) by Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach
+1. **[GPT NeoX Japanese](model_doc/gpt_neox_japanese)** (from ABEJA) released by Shinya Otani, Takayoshi Makabe, Anuj Arora, and Kyo Hattori.
+1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
+1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
+1. **[GPT-Sw3](model_doc/gpt-sw3)** (from AI-Sweden) released with the paper [Lessons Learned from GPT-SW3: Building the First Large-Scale Generative Language Model for Swedish](http://www.lrec-conf.org/proceedings/lrec2022/pdf/2022.lrec-1.376.pdf) by Ariel Ekgren, Amaru Cuba Gyllensten, Evangelia Gogoulou, Alice Heiman, Severine Verlinden, Joey Öhman, Fredrik Carlsson, Magnus Sahlgren.
+1. **[GPTBigCode](model_doc/gpt_bigcode)** (from BigCode) released with the paper [SantaCoder: don't reach for the stars!](https://arxiv.org/abs/2301.03988) by Loubna Ben Allal, Raymond Li, Denis Kocetkov, Chenghao Mou, Christopher Akiki, Carlos Munoz Ferrandis, Niklas Muennighoff, Mayank Mishra, Alex Gu, Manan Dey, Logesh Kumar Umapathi, Carolyn Jane Anderson, Yangtian Zi, Joel Lamy Poirier, Hailey Schoelkopf, Sergey Troshin, Dmitry Abulkhanov, Manuel Romero, Michael Lappert, Francesco De Toni, Bernardo García del Río, Qian Liu, Shamik Bose, Urvashi Bhattacharyya, Terry Yue Zhuo, Ian Yu, Paulo Villegas, Marco Zocca, Sourab Mangrulkar, David Lansky, Huu Nguyen, Danish Contractor, Luis Villa, Jia Li, Dzmitry Bahdanau, Yacine Jernite, Sean Hughes, Daniel Fried, Arjun Guha, Harm de Vries, Leandro von Werra.
+1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released in the repository [tanreinama/GPTSAN](https://github.com/tanreinama/GPTSAN/blob/main/report/model.md) by Toshiyuki Sakamoto(tanreinama).
+1. **[Graphormer](model_doc/graphormer)** (from Microsoft) released with the paper [Do Transformers Really Perform Bad for Graph Representation?](https://arxiv.org/abs/2106.05234) by Chengxuan Ying, Tianle Cai, Shengjie Luo, Shuxin Zheng, Guolin Ke, Di He, Yanming Shen, Tie-Yan Liu.
+1. **[GroupViT](model_doc/groupvit)** (from UCSD, NVIDIA) released with the paper [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://arxiv.org/abs/2202.11094) by Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang.
+1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
+1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
+1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
+1. **[Informer](model_doc/informer)** (from Beihang University, UC Berkeley, Rutgers University, SEDD Company) released with the paper [Informer: Beyond Efficient Transformer for Long Sequence Time-Series Forecasting](https://arxiv.org/abs/2012.07436) by Haoyi Zhou, Shanghang Zhang, Jieqi Peng, Shuai Zhang, Jianxin Li, Hui Xiong, and Wancai Zhang.
+1. **[Jukebox](model_doc/jukebox)** (from OpenAI) released with the paper [Jukebox: A Generative Model for Music](https://arxiv.org/pdf/2005.00341.pdf) by Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford, Ilya Sutskever.
+1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
+1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
+1. **[LayoutLMv3](model_doc/layoutlmv3)** (from Microsoft Research Asia) released with the paper [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://arxiv.org/abs/2204.08387) by Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
+1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
+1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LeViT](model_doc/levit)** (from Meta AI) released with the paper [LeViT: A Vision Transformer in ConvNet's Clothing for Faster Inference](https://arxiv.org/abs/2104.01136) by Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze.
+1. **[LiLT](model_doc/lilt)** (from South China University of Technology) released with the paper [LiLT: A Simple yet Effective Language-Independent Layout Transformer for Structured Document Understanding](https://arxiv.org/abs/2202.13669) by Jiapeng Wang, Lianwen Jin, Kai Ding.
+1. **[LLaMA](model_doc/llama)** (from The FAIR team of Meta AI) released with the paper [LLaMA: Open and Efficient Foundation Language Models](https://arxiv.org/abs/2302.13971) by Hugo Touvron, Thibaut Lavril, Gautier Izacard, Xavier Martinet, Marie-Anne Lachaux, Timothée Lacroix, Baptiste Rozière, Naman Goyal, Eric Hambro, Faisal Azhar, Aurelien Rodriguez, Armand Joulin, Edouard Grave, Guillaume Lample.
+1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LongT5](model_doc/longt5)** (from Google AI) released with the paper [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://arxiv.org/abs/2112.07916) by Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung, Yinfei Yang.
+1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
+1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490) by Hao Tan and Mohit Bansal.
+1. **[M-CTC-T](model_doc/mctct)** (from Facebook) released with the paper [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://arxiv.org/abs/2111.00161) by Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert.
+1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
+1. **[MarkupLM](model_doc/markuplm)** (from Microsoft Research Asia) released with the paper [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document Understanding](https://arxiv.org/abs/2110.08518) by Junlong Li, Yiheng Xu, Lei Cui, Furu Wei.
+1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
+1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
+1. **[MatCha](model_doc/matcha)** (from Google AI) released with the paper [MatCha: Enhancing Visual Language Pretraining with Math Reasoning and Chart Derendering](https://arxiv.org/abs/2212.09662) by Fangyu Liu, Francesco Piccinno, Syrine Krichene, Chenxi Pang, Kenton Lee, Mandar Joshi, Yasemin Altun, Nigel Collier, Julian Martin Eisenschlos.
+1. **[mBART](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+1. **[mBART-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
+1. **[MEGA](model_doc/mega)** (from Meta/USC/CMU/SJTU) released with the paper [Mega: Moving Average Equipped Gated Attention](https://arxiv.org/abs/2209.10655) by Xuezhe Ma, Chunting Zhou, Xiang Kong, Junxian He, Liangke Gui, Graham Neubig, Jonathan May, and Luke Zettlemoyer.
+1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[MGP-STR](model_doc/mgp-str)** (from Alibaba Research) released with the paper [Multi-Granularity Prediction for Scene Text Recognition](https://arxiv.org/abs/2209.03592) by Peng Wang, Cheng Da, and Cong Yao.
+1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
+1. **[MobileBERT](model_doc/mobilebert)** (from CMU/Google Brain) released with the paper [MobileBERT: a Compact Task-Agnostic BERT for Resource-Limited Devices](https://arxiv.org/abs/2004.02984) by Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny Zhou.
+1. **[MobileNetV1](model_doc/mobilenet_v1)** (from Google Inc.) released with the paper [MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications](https://arxiv.org/abs/1704.04861) by Andrew G. Howard, Menglong Zhu, Bo Chen, Dmitry Kalenichenko, Weijun Wang, Tobias Weyand, Marco Andreetto, Hartwig Adam.
+1. **[MobileNetV2](model_doc/mobilenet_v2)** (from Google Inc.) released with the paper [MobileNetV2: Inverted Residuals and Linear Bottlenecks](https://arxiv.org/abs/1801.04381) by Mark Sandler, Andrew Howard, Menglong Zhu, Andrey Zhmoginov, Liang-Chieh Chen.
+1. **[MobileViT](model_doc/mobilevit)** (from Apple) released with the paper [MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer](https://arxiv.org/abs/2110.02178) by Sachin Mehta and Mohammad Rastegari.
+1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
+1. **[MVP](model_doc/mvp)** (from RUC AI Box) released with the paper [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://arxiv.org/abs/2206.12131) by Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen.
+1. **[NAT](model_doc/nat)** (from SHI Labs) released with the paper [Neighborhood Attention Transformer](https://arxiv.org/abs/2204.07143) by Ali Hassani, Steven Walton, Jiachen Li, Shen Li, and Humphrey Shi.
+1. **[Nezha](model_doc/nezha)** (from Huawei Noah’s Ark Lab) released with the paper [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://arxiv.org/abs/1909.00204) by Junqiu Wei, Xiaozhe Ren, Xiaoguang Li, Wenyong Huang, Yi Liao, Yasheng Wang, Jiashu Lin, Xin Jiang, Xiao Chen and Qun Liu.
+1. **[NLLB](model_doc/nllb)** (from Meta) released with the paper [No Language Left Behind: Scaling Human-Centered Machine Translation](https://arxiv.org/abs/2207.04672) by the NLLB team.
+1. **[NLLB-MOE](model_doc/nllb-moe)** (from Meta) released with the paper [No Language Left Behind: Scaling Human-Centered Machine Translation](https://arxiv.org/abs/2207.04672) by the NLLB team.
+1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
+1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
+1. **[OpenLlama](model_doc/open-llama)** (from [s-JoL](https://huggingface.co/s-JoL)) released on GitHub (now removed).
+1. **[OPT](master/model_doc/opt)** (from Meta AI) released with the paper [OPT: Open Pre-trained Transformer Language Models](https://arxiv.org/abs/2205.01068) by Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al.
+1. **[OWL-ViT](model_doc/owlvit)** (from Google AI) released with the paper [Simple Open-Vocabulary Object Detection with Vision Transformers](https://arxiv.org/abs/2205.06230) by Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby.
+1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
+1. **[PEGASUS-X](model_doc/pegasus_x)** (from Google) released with the paper [Investigating Efficiently Extending Transformers for Long Input Summarization](https://arxiv.org/abs/2208.04347) by Jason Phang, Yao Zhao, and Peter J. Liu.
+1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
+1. **[Pix2Struct](model_doc/pix2struct)** (from Google) released with the paper [Pix2Struct: Screenshot Parsing as Pretraining for Visual Language Understanding](https://arxiv.org/abs/2210.03347) by Kenton Lee, Mandar Joshi, Iulia Turc, Hexiang Hu, Fangyu Liu, Julian Eisenschlos, Urvashi Khandelwal, Peter Shaw, Ming-Wei Chang, Kristina Toutanova.
+1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
+1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
+1. **[RAG](model_doc/rag)** (from Facebook) released with the paper [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://arxiv.org/abs/2005.11401) by Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela.
+1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
+1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://arxiv.org/abs/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
+1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
+1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
+1. **[RoBERTa-PreLayerNorm](model_doc/roberta-prelayernorm)** (from Facebook) released with the paper [fairseq: A Fast, Extensible Toolkit for Sequence Modeling](https://arxiv.org/abs/1904.01038) by Myle Ott, Sergey Edunov, Alexei Baevski, Angela Fan, Sam Gross, Nathan Ng, David Grangier, Michael Auli.
+1. **[RoCBert](model_doc/roc_bert)** (from WeChatAI) released with the paper [RoCBert: Robust Chinese Bert with Multimodal Contrastive Pretraining](https://aclanthology.org/2022.acl-long.65.pdf) by HuiSu, WeiweiShi, XiaoyuShen, XiaoZhou, TuoJi, JiaruiFang, JieZhou.
+1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
+1. **[RWKV](model_doc/rwkv)** (from Bo Peng), released on [this repo](https://github.com/BlinkDL/RWKV-LM) by Bo Peng.
+1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
+1. **[Segment Anything](model_doc/sam)** (from Meta AI) released with the paper [Segment Anything](https://arxiv.org/pdf/2304.02643v1.pdf) by Alexander Kirillov, Eric Mintun, Nikhila Ravi, Hanzi Mao, Chloe Rolland, Laura Gustafson, Tete Xiao, Spencer Whitehead, Alex Berg, Wan-Yen Lo, Piotr Dollar, Ross Girshick.
+1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SpeechT5](model_doc/speecht5)** (from Microsoft Research) released with the paper [SpeechT5: Unified-Modal Encoder-Decoder Pre-Training for Spoken Language Processing](https://arxiv.org/abs/2110.07205) by Junyi Ao, Rui Wang, Long Zhou, Chengyi Wang, Shuo Ren, Yu Wu, Shujie Liu, Tom Ko, Qing Li, Yu Zhang, Zhihua Wei, Yao Qian, Jinyu Li, Furu Wei.
+1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
+1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
+1. **[SqueezeBERT](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
+1. **[SwiftFormer](model_doc/swiftformer)** (from MBZUAI) released with the paper [SwiftFormer: Efficient Additive Attention for Transformer-based Real-time Mobile Vision Applications](https://arxiv.org/abs/2303.15446) by Abdelrahman Shaker, Muhammad Maaz, Hanoona Rasheed, Salman Khan, Ming-Hsuan Yang, Fahad Shahbaz Khan.
+1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+1. **[Swin Transformer V2](model_doc/swinv2)** (from Microsoft) released with the paper [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883) by Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo.
+1. **[Swin2SR](model_doc/swin2sr)** (from University of Würzburg) released with the paper [Swin2SR: SwinV2 Transformer for Compressed Image Super-Resolution and Restoration](https://arxiv.org/abs/2209.11345) by Marcos V. Conde, Ui-Jin Choi, Maxime Burchi, Radu Timofte.
+1. **[SwitchTransformers](model_doc/switch_transformers)** (from Google) released with the paper [Switch Transformers: Scaling to Trillion Parameter Models with Simple and Efficient Sparsity](https://arxiv.org/abs/2101.03961) by William Fedus, Barret Zoph, Noam Shazeer.
+1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[Table Transformer](model_doc/table-transformer)** (from Microsoft Research) released with the paper [PubTables-1M: Towards Comprehensive Table Extraction From Unstructured Documents](https://arxiv.org/abs/2110.00061) by Brandon Smock, Rohith Pesala, Robin Abraham.
+1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
+1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
+1. **[Time Series Transformer](model_doc/time_series_transformer)** (from HuggingFace).
+1. **[TimeSformer](model_doc/timesformer)** (from Facebook) released with the paper [Is Space-Time Attention All You Need for Video Understanding?](https://arxiv.org/abs/2102.05095) by Gedas Bertasius, Heng Wang, Lorenzo Torresani.
+1. **[Trajectory Transformer](model_doc/trajectory_transformers)** (from the University of California at Berkeley) released with the paper [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://arxiv.org/abs/2106.02039) by Michael Janner, Qiyang Li, Sergey Levine
+1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
+1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
+1. **[TVLT](model_doc/tvlt)** (from UNC Chapel Hill) released with the paper [TVLT: Textless Vision-Language Transformer](https://arxiv.org/abs/2209.14156) by Zineng Tang, Jaemin Cho, Yixin Nie, Mohit Bansal.
+1. **[TVP](model_doc/tvp)** (from Intel) released with the paper [Text-Visual Prompting for Efficient 2D Temporal Video Grounding](https://arxiv.org/abs/2303.04995) by Yimeng Zhang, Xin Chen, Jinghan Jia, Sijia Liu, Ke Ding.
+1. **[UL2](model_doc/ul2)** (from Google Research) released with the paper [Unifying Language Learning Paradigms](https://arxiv.org/abs/2205.05131v1) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler
+1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
+1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
+1. **[UPerNet](model_doc/upernet)** (from Peking University) released with the paper [Unified Perceptual Parsing for Scene Understanding](https://arxiv.org/abs/1807.10221) by Tete Xiao, Yingcheng Liu, Bolei Zhou, Yuning Jiang, Jian Sun.
+1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://arxiv.org/abs/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+1. **[VideoMAE](model_doc/videomae)** (from Multimedia Computing Group, Nanjing University) released with the paper [VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training](https://arxiv.org/abs/2203.12602) by Zhan Tong, Yibing Song, Jue Wang, Limin Wang.
+1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
+1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
+1. **[ViT Hybrid](model_doc/vit_hybrid)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
+1. **[ViTMSN](model_doc/vit_msn)** (from Meta AI) released with the paper [Masked Siamese Networks for Label-Efficient Learning](https://arxiv.org/abs/2204.07141) by Mahmoud Assran, Mathilde Caron, Ishan Misra, Piotr Bojanowski, Florian Bordes, Pascal Vincent, Armand Joulin, Michael Rabbat, Nicolas Ballas.
+1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
+1. **[Wav2Vec2-Conformer](model_doc/wav2vec2-conformer)** (from Facebook AI) released with the paper [FAIRSEQ S2T: Fast Speech-to-Text Modeling with FAIRSEQ](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Sravya Popuri, Dmytro Okhonko, Juan Pino.
+1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
+1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
+1. **[Whisper](model_doc/whisper)** (from OpenAI) released with the paper [Robust Speech Recognition via Large-Scale Weak Supervision](https://cdn.openai.com/papers/whisper.pdf) by Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever.
+1. **[X-CLIP](model_doc/xclip)** (from Microsoft Research) released with the paper [Expanding Language-Image Pretrained Models for General Video Recognition](https://arxiv.org/abs/2208.02816) by Bolin Ni, Houwen Peng, Minghao Chen, Songyang Zhang, Gaofeng Meng, Jianlong Fu, Shiming Xiang, Haibin Ling.
+1. **[X-MOD](model_doc/xmod)** (from Meta AI) released with the paper [Lifting the Curse of Multilinguality by Pre-training Modular Transformers](http://dx.doi.org/10.18653/v1/2022.naacl-main.255) by Jonas Pfeiffer, Naman Goyal, Xi Lin, Xian Li, James Cross, Sebastian Riedel, Mikel Artetxe.
+1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
+1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291) by Guillaume Lample and Alexis Conneau.
+1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
+1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
+1. **[XLM-V](model_doc/xlm-v)** (from Meta AI) released with the paper [XLM-V: Overcoming the Vocabulary Bottleneck in Multilingual Masked Language Models](https://arxiv.org/abs/2301.10472) by Davis Liang, Hila Gonen, Yuning Mao, Rui Hou, Naman Goyal, Marjan Ghazvininejad, Luke Zettlemoyer, Madian Khabsa.
+1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
+1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
+1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
+1. **[YOLOS](model_doc/yolos)** (from Huazhong University of Science & Technology) released with the paper [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://arxiv.org/abs/2106.00666) by Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu.
+1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
+
+
+### Rangka kerja yang disokong
+
+Jadual di bawah mewakili sokongan semasa dalam perpustakaan untuk setiap model tersebut, sama ada model tersebut mempunyai Python
+tokenizer (dipanggil ""lambat""). Tokenizer ""pantas"" yang disokong oleh perpustakaan Tokenizers 🤗, sama ada mereka mempunyai sokongan dalam Jax (melalui
+Flax), PyTorch, dan/atau TensorFlow.
+
+
+
+| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:-----------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| ALIGN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| AltCLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Audio Spectrogram Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Autoformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBird-Pegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BioGpt | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BiT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BLIP | ❌ | ❌ | ✅ | ✅ | ❌ |
+| BLIP-2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| BLOOM | ❌ | ✅ | ✅ | ❌ | ❌ |
+| BridgeTower | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Bros | ✅ | ✅ | ✅ | ❌ | ❌ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| CANINE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Chinese-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CLAP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CLIPSeg | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CodeGen | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Conditional DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNeXT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| ConvNeXTV2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CPM-Ant | ✅ | ❌ | ✅ | ❌ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| CvT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Deformable DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DETA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DiNAT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DonutSwin | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| EfficientFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| EfficientNet | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ERNIE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ErnieM | ✅ | ❌ | ✅ | ❌ | ❌ |
+| ESM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FLAVA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| FocalNet | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GIT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
+| GPT NeoX Japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| GPT-Sw3 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| GPTBigCode | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPTSAN-japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Graphormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GroupViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Informer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Jukebox | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LayoutLMv3 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LeViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LiLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LLaMA | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LongT5 | ❌ | ❌ | ✅ | ❌ | ✅ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M-CTC-T | ❌ | ❌ | ✅ | ❌ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MarkupLM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Mask2Former | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MaskFormerSwin | ❌ | ❌ | ❌ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MEGA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Megatron-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MGP-STR | ✅ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MobileNetV1 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileNetV2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MVP | ✅ | ✅ | ✅ | ❌ | ❌ |
+| NAT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Nezha | ❌ | ❌ | ✅ | ❌ | ❌ |
+| NLLB-MOE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Nyströmformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OneFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| OpenLlama | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OPT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| OWL-ViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| PEGASUS-X | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Pix2Struct | ❌ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| REALM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoBERTa-PreLayerNorm | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RoCBert | ✅ | ❌ | ✅ | ❌ | ❌ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RWKV | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SAM | ❌ | ❌ | ✅ | ✅ | ❌ |
+| SegFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| SpeechT5 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SwiftFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Swin Transformer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Swin Transformer V2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Swin2SR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SwitchTransformers | ❌ | ❌ | ✅ | ❌ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Table Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Time Series Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TimeSformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TVLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TVP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UPerNet | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VideoMAE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisualBERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViT Hybrid | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| ViTMSN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Whisper | ✅ | ✅ | ✅ | ✅ | ✅ |
+| X-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| X-MOD | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/_config.py b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/_config.py
new file mode 100644
index 0000000000000000000000000000000000000000..f49e4e4731965a504b8da443c2cd979638cd22bb
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/_config.py
@@ -0,0 +1,14 @@
+# docstyle-ignore
+INSTALL_CONTENT = """
+# Transformers installation
+! pip install transformers datasets evaluate accelerate
+# To install from source instead of the last release, comment the command above and uncomment the following one.
+# ! pip install git+https://github.com/huggingface/transformers.git
+"""
+
+notebook_first_cells = [{"type": "code", "content": INSTALL_CONTENT}]
+black_avoid_patterns = {
+ "{processor_class}": "FakeProcessorClass",
+ "{model_class}": "FakeModelClass",
+ "{object_class}": "FakeObjectClass",
+}
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/_toctree.yml b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..d042168f7b9b693d92c0f85e2142ca1ec43e1236
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/_toctree.yml
@@ -0,0 +1,38 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers
+ - local: quicktour
+ title: Tour rápido
+ - local: installation
+ title: Instalação
+ title: Início
+- sections:
+ - local: pipeline_tutorial
+ title: Pipelines para inferência
+ - local: training
+ title: Fine-tuning de um modelo pré-treinado
+ - local: accelerate
+ title: Treinamento distribuído com 🤗 Accelerate
+ title: Tutoriais
+- sections:
+ - local: fast_tokenizers
+ title: Usando os Tokenizers do 🤗 Tokenizers
+ - local: create_a_model
+ title: Criando uma arquitetura customizada
+ - local: custom_models
+ title: Compartilhando modelos customizados
+ - local: run_scripts
+ title: Treinamento a partir de um script
+ - local: converting_tensorflow_models
+ title: Convertendo checkpoints do TensorFlow para Pytorch
+ - local: serialization
+ title: Exportando modelos para ONNX
+ - sections:
+ - local: tasks/sequence_classification
+ title: Classificação de texto
+ - local: tasks/token_classification
+ title: Classificação de tokens
+ title: Fine-tuning para tarefas específicas
+ - local: multilingual
+ title: Modelos multilinguísticos para inferência
+ title: Guias práticos
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/accelerate.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/accelerate.md
new file mode 100644
index 0000000000000000000000000000000000000000..a4e346a2b4873ff475ff9c3e34ff75e276fb58a7
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/accelerate.md
@@ -0,0 +1,145 @@
+
+
+# Treinamento distribuído com o 🤗 Accelerate
+
+O paralelismo surgiu como uma estratégia para treinar modelos grandes em hardware limitado e aumentar a velocidade
+de treinamento em várias órdens de magnitude. Na Hugging Face criamos a biblioteca [🤗 Accelerate](https://huggingface.co/docs/accelerate)
+para ajudar os usuários a treinar modelos 🤗 Transformers com qualquer configuração distribuída, seja em uma máquina
+com múltiplos GPUs ou em múltiplos GPUs distribuidos entre muitas máquinas. Neste tutorial, você irá aprender como
+personalizar seu laço de treinamento de PyTorch para poder treinar em ambientes distribuídos.
+
+## Configuração
+
+De início, instale o 🤗 Accelerate:
+
+```bash
+pip install accelerate
+```
+
+Logo, devemos importar e criar um objeto [`Accelerator`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator).
+O `Accelerator` detectará automáticamente a configuração distribuída disponível e inicializará todos os
+componentes necessários para o treinamento. Não há necessidade portanto de especificar o dispositivo onde deve colocar seu modelo.
+
+```py
+>>> from accelerate import Accelerator
+
+>>> accelerator = Accelerator()
+```
+
+## Preparando a aceleração
+
+Passe todos os objetos relevantes ao treinamento para o método [`prepare`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator.prepare).
+Isto inclui os DataLoaders de treino e evaluação, um modelo e um otimizador:
+
+```py
+>>> train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
+... train_dataloader, eval_dataloader, model, optimizer
+... )
+```
+
+## Backward
+
+Por último, substitua o `loss.backward()` padrão em seu laço de treinamento com o método [`backward`](https://huggingface.co/docs/accelerate/package_reference/accelerator#accelerate.Accelerator.backward) do 🤗 Accelerate:
+
+```py
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... outputs = model(**batch)
+... loss = outputs.loss
+... accelerator.backward(loss)
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+Como se poder ver no seguinte código, só precisará adicionar quatro linhas de código ao seu laço de treinamento
+para habilitar o treinamento distribuído!
+
+```diff
++ from accelerate import Accelerator
+ from transformers import AdamW, AutoModelForSequenceClassification, get_scheduler
+
++ accelerator = Accelerator()
+
+ model = AutoModelForSequenceClassification.from_pretrained(checkpoint, num_labels=2)
+ optimizer = AdamW(model.parameters(), lr=3e-5)
+
+- device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+- model.to(device)
+
++ train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
++ train_dataloader, eval_dataloader, model, optimizer
++ )
+
+ num_epochs = 3
+ num_training_steps = num_epochs * len(train_dataloader)
+ lr_scheduler = get_scheduler(
+ "linear",
+ optimizer=optimizer,
+ num_warmup_steps=0,
+ num_training_steps=num_training_steps
+ )
+
+ progress_bar = tqdm(range(num_training_steps))
+
+ model.train()
+ for epoch in range(num_epochs):
+ for batch in train_dataloader:
+- batch = {k: v.to(device) for k, v in batch.items()}
+ outputs = model(**batch)
+ loss = outputs.loss
+- loss.backward()
++ accelerator.backward(loss)
+
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ progress_bar.update(1)
+```
+
+## Treinamento
+
+Quando tiver adicionado as linhas de código relevantes, inicie o treinamento por um script ou notebook como o Colab.
+
+### Treinamento em um Script
+
+Se estiver rodando seu treinamento em um Script, execute o seguinte comando para criar e guardar um arquivo de configuração:
+
+```bash
+accelerate config
+```
+
+Comece o treinamento com:
+
+```bash
+accelerate launch train.py
+```
+
+### Treinamento em um Notebook
+
+O 🤗 Accelerate pode rodar em um notebook, por exemplo, se estiver planejando usar as TPUs do Google Colab.
+Encapsule o código responsável pelo treinamento de uma função e passe-o ao `notebook_launcher`:
+
+```py
+>>> from accelerate import notebook_launcher
+
+>>> notebook_launcher(training_function)
+```
+
+Para obter mais informações sobre o 🤗 Accelerate e suas numerosas funções, consulte a [documentación](https://huggingface.co/docs/accelerate/index).
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/converting_tensorflow_models.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/converting_tensorflow_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..63e926d4dcfe6c2a8c65c112a37b0a42f77786d5
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/converting_tensorflow_models.md
@@ -0,0 +1,152 @@
+
+
+# Convertendo checkpoints do TensorFlow para Pytorch
+
+Uma interface de linha de comando é fornecida para converter os checkpoints originais Bert/GPT/GPT-2/Transformer-XL/XLNet/XLM em modelos
+que podem ser carregados usando os métodos `from_pretrained` da biblioteca.
+
+
+
+A partir da versão 2.3.0 o script de conversão agora faz parte do transformers CLI (**transformers-cli**) disponível em qualquer instalação
+transformers >= 2.3.0.
+
+A documentação abaixo reflete o formato do comando **transformers-cli convert**.
+
+
+
+## BERT
+
+Você pode converter qualquer checkpoint do BERT em TensorFlow (em particular [os modelos pré-treinados lançados pelo Google](https://github.com/google-research/bert#pre-trained-models)) em um arquivo PyTorch usando um
+[convert_bert_original_tf_checkpoint_to_pytorch.py](https://github.com/huggingface/transformers/tree/main/src/transformers/models/bert/convert_bert_original_tf_checkpoint_to_pytorch.py) script.
+
+Esta Interface de Linha de Comando (CLI) recebe como entrada um checkpoint do TensorFlow (três arquivos começando com `bert_model.ckpt`) e o
+arquivo de configuração (`bert_config.json`), e então cria um modelo PyTorch para esta configuração, carrega os pesos
+do checkpoint do TensorFlow no modelo PyTorch e salva o modelo resultante em um arquivo PyTorch que pode
+ser importado usando `from_pretrained()` (veja o exemplo em [quicktour](quicktour) , [run_glue.py](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-classification/run_glue.py) ).
+
+Você só precisa executar este script de conversão **uma vez** para obter um modelo PyTorch. Você pode então desconsiderar o checkpoint em
+ TensorFlow (os três arquivos começando com `bert_model.ckpt`), mas certifique-se de manter o arquivo de configuração (\
+`bert_config.json`) e o arquivo de vocabulário (`vocab.txt`), pois eles também são necessários para o modelo PyTorch.
+
+Para executar este script de conversão específico, você precisará ter o TensorFlow e o PyTorch instalados (`pip install tensorflow`). O resto do repositório requer apenas o PyTorch.
+
+Aqui está um exemplo do processo de conversão para um modelo `BERT-Base Uncased` pré-treinado:
+
+```bash
+export BERT_BASE_DIR=/path/to/bert/uncased_L-12_H-768_A-12
+
+transformers-cli convert --model_type bert \
+ --tf_checkpoint $BERT_BASE_DIR/bert_model.ckpt \
+ --config $BERT_BASE_DIR/bert_config.json \
+ --pytorch_dump_output $BERT_BASE_DIR/pytorch_model.bin
+```
+
+Você pode baixar os modelos pré-treinados do Google para a conversão [aqui](https://github.com/google-research/bert#pre-trained-models).
+
+## ALBERT
+
+Converta os checkpoints do modelo ALBERT em TensorFlow para PyTorch usando o
+[convert_albert_original_tf_checkpoint_to_pytorch.py](https://github.com/huggingface/transformers/tree/main/src/transformers/models/albert/convert_albert_original_tf_checkpoint_to_pytorch.py) script.
+
+A Interface de Linha de Comando (CLI) recebe como entrada um checkpoint do TensorFlow (três arquivos começando com `model.ckpt-best`) e o
+arquivo de configuração (`albert_config.json`), então cria e salva um modelo PyTorch. Para executar esta conversão, você
+precisa ter o TensorFlow e o PyTorch instalados.
+
+Aqui está um exemplo do processo de conversão para o modelo `ALBERT Base` pré-treinado:
+
+```bash
+export ALBERT_BASE_DIR=/path/to/albert/albert_base
+
+transformers-cli convert --model_type albert \
+ --tf_checkpoint $ALBERT_BASE_DIR/model.ckpt-best \
+ --config $ALBERT_BASE_DIR/albert_config.json \
+ --pytorch_dump_output $ALBERT_BASE_DIR/pytorch_model.bin
+```
+
+Você pode baixar os modelos pré-treinados do Google para a conversão [aqui](https://github.com/google-research/albert#pre-trained-models).
+
+## OpenAI GPT
+
+Aqui está um exemplo do processo de conversão para um modelo OpenAI GPT pré-treinado, supondo que seu checkpoint NumPy
+foi salvo com o mesmo formato do modelo pré-treinado OpenAI (veja [aqui](https://github.com/openai/finetune-transformer-lm)\
+)
+
+```bash
+export OPENAI_GPT_CHECKPOINT_FOLDER_PATH=/path/to/openai/pretrained/numpy/weights
+
+transformers-cli convert --model_type gpt \
+ --tf_checkpoint $OPENAI_GPT_CHECKPOINT_FOLDER_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT \
+ [--config OPENAI_GPT_CONFIG] \
+ [--finetuning_task_name OPENAI_GPT_FINETUNED_TASK] \
+```
+
+## OpenAI GPT-2
+
+Aqui está um exemplo do processo de conversão para um modelo OpenAI GPT-2 pré-treinado (consulte [aqui](https://github.com/openai/gpt-2))
+
+```bash
+export OPENAI_GPT2_CHECKPOINT_PATH=/path/to/openai-community/gpt2/pretrained/weights
+
+transformers-cli convert --model_type gpt2 \
+ --tf_checkpoint $OPENAI_GPT2_CHECKPOINT_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT \
+ [--config OPENAI_GPT2_CONFIG] \
+ [--finetuning_task_name OPENAI_GPT2_FINETUNED_TASK]
+```
+
+## XLNet
+
+Aqui está um exemplo do processo de conversão para um modelo XLNet pré-treinado:
+
+```bash
+export TRANSFO_XL_CHECKPOINT_PATH=/path/to/xlnet/checkpoint
+export TRANSFO_XL_CONFIG_PATH=/path/to/xlnet/config
+
+transformers-cli convert --model_type xlnet \
+ --tf_checkpoint $TRANSFO_XL_CHECKPOINT_PATH \
+ --config $TRANSFO_XL_CONFIG_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT \
+ [--finetuning_task_name XLNET_FINETUNED_TASK] \
+```
+
+## XLM
+
+Aqui está um exemplo do processo de conversão para um modelo XLM pré-treinado:
+
+```bash
+export XLM_CHECKPOINT_PATH=/path/to/xlm/checkpoint
+
+transformers-cli convert --model_type xlm \
+ --tf_checkpoint $XLM_CHECKPOINT_PATH \
+ --pytorch_dump_output $PYTORCH_DUMP_OUTPUT
+ [--config XML_CONFIG] \
+ [--finetuning_task_name XML_FINETUNED_TASK]
+```
+
+## T5
+
+Aqui está um exemplo do processo de conversão para um modelo T5 pré-treinado:
+
+```bash
+export T5=/path/to/t5/uncased_L-12_H-768_A-12
+
+transformers-cli convert --model_type t5 \
+ --tf_checkpoint $T5/t5_model.ckpt \
+ --config $T5/t5_config.json \
+ --pytorch_dump_output $T5/pytorch_model.bin
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/create_a_model.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/create_a_model.md
new file mode 100644
index 0000000000000000000000000000000000000000..dd71963236f4fa9eb37add6c04ebd4b967069175
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/create_a_model.md
@@ -0,0 +1,359 @@
+
+
+# Criar uma arquitetura customizada
+
+Uma [`AutoClass`](model_doc/auto) automaticamente infere a arquitetura do modelo e baixa configurações e pesos pré-treinados. Geralmente, nós recomendamos usar uma `AutoClass` para produzir um código independente de checkpoints. Mas usuários que querem mais contole sobre parâmetros específicos do modelo pode criar um modelo customizado 🤗 Transformers a partir de algumas classes bases. Isso pode ser particulamente útil para alguém que está interessado em estudar, treinar ou fazer experimentos com um modelo 🤗 Transformers. Nesse tutorial, será explicado como criar um modelo customizado sem uma `AutoClass`. Aprenda como:
+
+- Carregar e customizar a configuração de um modelo.
+- Criar a arquitetura de um modelo.
+- Criar um tokenizer rápido e devagar para textos.
+- Criar extrator de features para tarefas envolvendo audio e imagem.
+- Criar um processador para tarefas multimodais.
+
+## configuration
+
+A [configuration](main_classes/configuration) refere-se a atributos específicos de um modelo. Cada configuração de modelo tem atributos diferentes; por exemplo, todos modelo de PLN possuem os atributos `hidden_size`, `num_attention_heads`, `num_hidden_layers` e `vocab_size` em comum. Esse atributos especificam o numero de 'attention heads' ou 'hidden layers' para construir um modelo.
+
+Dê uma olhada a mais em [DistilBERT](model_doc/distilbert) acessando [`DistilBertConfig`] para observar esses atributos:
+
+```py
+>>> from transformers import DistilBertConfig
+
+>>> config = DistilBertConfig()
+>>> print(config)
+DistilBertConfig {
+ "activation": "gelu",
+ "attention_dropout": 0.1,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+[`DistilBertConfig`] mostra todos os atributos padrões usados para construir um [`DistilBertModel`] base. Todos atributos são customizáveis, o que cria espaço para experimentos. Por exemplo, você pode customizar um modelo padrão para:
+
+- Tentar uma função de ativação diferente com o parâmetro `activation`.
+- Usar uma taxa de desistência maior para as probabilidades de 'attention' com o parâmetro `attention_dropout`.
+
+```py
+>>> my_config = DistilBertConfig(activation="relu", attention_dropout=0.4)
+>>> print(my_config)
+DistilBertConfig {
+ "activation": "relu",
+ "attention_dropout": 0.4,
+ "dim": 768,
+ "dropout": 0.1,
+ "hidden_dim": 3072,
+ "initializer_range": 0.02,
+ "max_position_embeddings": 512,
+ "model_type": "distilbert",
+ "n_heads": 12,
+ "n_layers": 6,
+ "pad_token_id": 0,
+ "qa_dropout": 0.1,
+ "seq_classif_dropout": 0.2,
+ "sinusoidal_pos_embds": false,
+ "transformers_version": "4.16.2",
+ "vocab_size": 30522
+}
+```
+
+Atributos de um modelo pré-treinado podem ser modificados na função [`~PretrainedConfig.from_pretrained`]:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("distilbert/distilbert-base-uncased", activation="relu", attention_dropout=0.4)
+```
+
+Uma vez que você está satisfeito com as configurações do seu modelo, você consegue salvar elas com [`~PretrainedConfig.save_pretrained`]. Seu arquivo de configurações está salvo como um arquivo JSON no diretório especificado:
+
+```py
+>>> my_config.save_pretrained(save_directory="./your_model_save_path")
+```
+
+Para reusar o arquivo de configurações, carregue com [`~PretrainedConfig.from_pretrained`]:
+
+```py
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+```
+
+
+
+Você pode também salvar seu arquivo de configurações como um dicionário ou até mesmo com a diferença entre as seus atributos de configuração customizados e os atributos de configuração padrões! Olhe a documentação [configuration](main_classes/configuration) para mais detalhes.
+
+
+
+## Modelo
+
+O próximo passo é criar um [model](main_classes/models). O modelo - também vagamente referido como arquitetura - define o que cada camada está fazendo e quais operações estão acontecendo. Atributos como `num_hidden_layers` das configurações são utilizados para definir a arquitetura. Todo modelo compartilha a classe base [`PreTrainedModel`] e alguns métodos em comum como redimensionar o tamanho dos embeddings de entrada e podar as 'self-attention heads'. Além disso, todos os modelos também são subclasses de [`torch.nn.Module`](https://pytorch.org/docs/stable/generated/torch.nn.Module.html), [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) ou [`flax.linen.Module`](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html). Isso significa que os modelos são compatíveis com cada respectivo uso de framework.
+
+
+
+Carregar seus atributos de configuração customizados em um modelo:
+
+```py
+>>> from transformers import DistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+>>> model = DistilBertModel(my_config)
+```
+
+Isso cria um modelo com valores aleatórios ao invés de pré-treinar os pesos. Você não irá conseguir usar usar esse modelo para nada útil ainda, até você treinar ele. Treino é um processo caro e demorado. Geralmente é melhor utilizar um modelo pré-treinado para obter melhores resultados mais rápido, enquanto usa apenas uma fração dos recursos necessários para treinar.
+
+Criar um modelo pré-treinado com [`~PreTrainedModel.from_pretrained`]:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Quando você carregar os pesos pré-treinados, a configuração padrão do modelo é automaticamente carregada se o modelo é provido pelo 🤗 Transformers. No entanto, você ainda consegue mudar - alguns ou todos - os atributos padrões de configuração do modelo com os seus próprio atributos, se você preferir:
+
+```py
+>>> model = DistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+Carregar os seus próprios atributos padrões de contiguração no modelo:
+
+```py
+>>> from transformers import TFDistilBertModel
+
+>>> my_config = DistilBertConfig.from_pretrained("./your_model_save_path/my_config.json")
+>>> tf_model = TFDistilBertModel(my_config)
+```
+
+Isso cria um modelo com valores aleatórios ao invés de pré-treinar os pesos. Você não irá conseguir usar usar esse modelo para nada útil ainda, até você treinar ele. Treino é um processo caro e demorado. Geralmente é melhor utilizar um modelo pré-treinado para obter melhores resultados mais rápido, enquanto usa apenas uma fração dos recursos necessários para treinar.
+
+Criar um modelo pré-treinado com [`~TFPreTrainedModel.from_pretrained`]:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Quando você carregar os pesos pré-treinados, a configuração padrão do modelo é automaticamente carregada se o modelo é provido pelo 🤗 Transformers. No entanto, você ainda consegue mudar - alguns ou todos - os atributos padrões de configuração do modelo com os seus próprio atributos, se você preferir:
+
+```py
+>>> tf_model = TFDistilBertModel.from_pretrained("distilbert/distilbert-base-uncased", config=my_config)
+```
+
+
+
+### Heads do modelo
+
+Neste ponto, você tem um modelo básico do DistilBERT que gera os *estados ocultos*. Os estados ocultos são passados como entrada para a head do moelo para produzir a saída final. 🤗 Transformers fornece uma head de modelo diferente para cada tarefa desde que o modelo suporte essa tarefa (por exemplo, você não consegue utilizar o modelo DistilBERT para uma tarefa de 'sequence-to-sequence' como tradução).
+
+
+
+Por exemplo, [`DistilBertForSequenceClassification`] é um modelo DistilBERT base com uma head de classificação de sequência. A head de calssificação de sequência é uma camada linear no topo das saídas agrupadas.
+
+```py
+>>> from transformers import DistilBertForSequenceClassification
+
+>>> model = DistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Reutilize facilmente esse ponto de parada para outra tarefe mudando para uma head de modelo diferente. Para uma tarefe de responder questões, você usaria a head do modelo [`DistilBertForQuestionAnswering`]. A head de responder questões é similar com a de classificação de sequências exceto o fato de que ela é uma camada no topo dos estados das saídas ocultas.
+
+```py
+>>> from transformers import DistilBertForQuestionAnswering
+
+>>> model = DistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+Por exemplo, [`TFDistilBertForSequenceClassification`] é um modelo DistilBERT base com uma head de classificação de sequência. A head de calssificação de sequência é uma camada linear no topo das saídas agrupadas.
+
+```py
+>>> from transformers import TFDistilBertForSequenceClassification
+
+>>> tf_model = TFDistilBertForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Reutilize facilmente esse ponto de parada para outra tarefe mudando para uma head de modelo diferente. Para uma tarefe de responder questões, você usaria a head do modelo [`TFDistilBertForQuestionAnswering`]. A head de responder questões é similar com a de classificação de sequências exceto o fato de que ela é uma camada no topo dos estados das saídas ocultas.
+
+```py
+>>> from transformers import TFDistilBertForQuestionAnswering
+
+>>> tf_model = TFDistilBertForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+## Tokenizer
+
+A útlima classe base que você precisa antes de usar um modelo para dados textuais é a [tokenizer](main_classes/tokenizer) para converter textos originais para tensores. Existem dois tipos de tokenizers que você pode usar com 🤗 Transformers:
+
+- [`PreTrainedTokenizer`]: uma implementação em Python de um tokenizer.
+- [`PreTrainedTokenizerFast`]: um tokenizer da nossa biblioteca [🤗 Tokenizer](https://huggingface.co/docs/tokenizers/python/latest/) baseada em Rust. Esse tipo de tokenizer é significantemente mais rapido - especialmente durante tokenization de codificação - devido a implementação em Rust. O tokenizer rápido tambem oferece métodos adicionais como *offset mapping* que mapeia tokens para suar palavras ou caracteres originais.
+
+Os dois tokenizers suporta métodos comuns como os de codificar e decodificar, adicionar novos tokens, e gerenciar tokens especiais.
+
+
+
+Nem todo modelo suporta um 'fast tokenizer'. De uma olhada aqui [table](index#supported-frameworks) pra checar se um modelo suporta 'fast tokenizer'.
+
+
+
+Se você treinou seu prórpio tokenizer, você pode criar um a partir do seu arquivo *vocabulary*:
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> my_tokenizer = DistilBertTokenizer(vocab_file="my_vocab_file.txt", do_lower_case=False, padding_side="left")
+```
+
+É importante lembrar que o vocabulário de um tokenizer customizado será diferente de um vocabulário gerado pelo tokenizer de um modelo pré treinado. Você precisa usar o vocabulário de um modelo pré treinado se você estiver usando um modelo pré treinado, caso contrário as entradas não farão sentido. Criando um tokenizer com um vocabulário de um modelo pré treinado com a classe [`DistilBertTokenizer`]:
+
+```py
+>>> from transformers import DistilBertTokenizer
+
+>>> slow_tokenizer = DistilBertTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Criando um 'fast tokenizer' com a classe [`DistilBertTokenizerFast`]:
+
+```py
+>>> from transformers import DistilBertTokenizerFast
+
+>>> fast_tokenizer = DistilBertTokenizerFast.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+
+
+Pos padrão, [`AutoTokenizer`] tentará carregar um 'fast tokenizer'. Você pode disabilitar esse comportamento colocando `use_fast=False` no `from_pretrained`.
+
+
+
+## Extrator de features
+
+Um extrator de features processa entradas de imagem ou áudio. Ele herda da classe base [`~feature_extraction_utils.FeatureExtractionMixin`], e pode também herdar da classe [`ImageFeatureExtractionMixin`] para processamento de features de imagem ou da classe [`SequenceFeatureExtractor`] para processamento de entradas de áudio.
+
+Dependendo do que você está trabalhando em um audio ou uma tarefa de visão, crie um estrator de features associado com o modelo que você está usando. Por exemplo, crie um [`ViTFeatureExtractor`] padrão se você estiver usando [ViT](model_doc/vit) para classificação de imagens:
+
+```py
+>>> from transformers import ViTFeatureExtractor
+
+>>> vit_extractor = ViTFeatureExtractor()
+>>> print(vit_extractor)
+ViTFeatureExtractor {
+ "do_normalize": true,
+ "do_resize": true,
+ "feature_extractor_type": "ViTFeatureExtractor",
+ "image_mean": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": 2,
+ "size": 224
+}
+```
+
+
+
+Se você não estiver procurando por nenhuma customização, apenas use o método `from_pretrained` para carregar parâmetros do modelo de extrator de features padrão.
+
+
+
+Modifique qualquer parâmetro dentre os [`ViTFeatureExtractor`] para criar seu extrator de features customizado.
+
+```py
+>>> from transformers import ViTFeatureExtractor
+
+>>> my_vit_extractor = ViTFeatureExtractor(resample="PIL.Image.BOX", do_normalize=False, image_mean=[0.3, 0.3, 0.3])
+>>> print(my_vit_extractor)
+ViTFeatureExtractor {
+ "do_normalize": false,
+ "do_resize": true,
+ "feature_extractor_type": "ViTFeatureExtractor",
+ "image_mean": [
+ 0.3,
+ 0.3,
+ 0.3
+ ],
+ "image_std": [
+ 0.5,
+ 0.5,
+ 0.5
+ ],
+ "resample": "PIL.Image.BOX",
+ "size": 224
+}
+```
+
+Para entradas de áutio, você pode criar um [`Wav2Vec2FeatureExtractor`] e customizar os parâmetros de uma forma similar:
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> w2v2_extractor = Wav2Vec2FeatureExtractor()
+>>> print(w2v2_extractor)
+Wav2Vec2FeatureExtractor {
+ "do_normalize": true,
+ "feature_extractor_type": "Wav2Vec2FeatureExtractor",
+ "feature_size": 1,
+ "padding_side": "right",
+ "padding_value": 0.0,
+ "return_attention_mask": false,
+ "sampling_rate": 16000
+}
+```
+
+## Processor
+
+Para modelos que suportam tarefas multimodais, 🤗 Transformers oferece uma classe processadora que convenientemente cobre um extrator de features e tokenizer dentro de um único objeto. Por exemplo, vamos usar o [`Wav2Vec2Processor`] para uma tarefa de reconhecimento de fala automática (ASR). ASR transcreve áudio para texto, então você irá precisar de um extrator de um features e um tokenizer.
+
+Crie um extrator de features para lidar com as entradas de áudio.
+
+```py
+>>> from transformers import Wav2Vec2FeatureExtractor
+
+>>> feature_extractor = Wav2Vec2FeatureExtractor(padding_value=1.0, do_normalize=True)
+```
+
+Crie um tokenizer para lidar com a entrada de textos:
+
+```py
+>>> from transformers import Wav2Vec2CTCTokenizer
+
+>>> tokenizer = Wav2Vec2CTCTokenizer(vocab_file="my_vocab_file.txt")
+```
+
+Combine o extrator de features e o tokenizer no [`Wav2Vec2Processor`]:
+
+```py
+>>> from transformers import Wav2Vec2Processor
+
+>>> processor = Wav2Vec2Processor(feature_extractor=feature_extractor, tokenizer=tokenizer)
+```
+
+Com duas classes básicas - configuração e modelo - e um preprocessamento de classe adicional (tokenizer, extrator de features, ou processador), você pode criar qualquer modelo que suportado por 🤗 Transformers. Qualquer uma dessas classes base são configuráveis, te permitindo usar os atributos específicos que você queira. Você pode facilmente preparar um modelo para treinamento ou modificar um modelo pré-treinado com poucas mudanças.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/custom_models.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/custom_models.md
new file mode 100644
index 0000000000000000000000000000000000000000..27633f9d1bb238751ab0e49a254c0bec28ae4013
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/custom_models.md
@@ -0,0 +1,358 @@
+
+
+# Compartilhando modelos customizados
+
+A biblioteca 🤗 Transformers foi projetada para ser facilmente extensível. Cada modelo é totalmente codificado em uma determinada subpasta
+do repositório sem abstração, para que você possa copiar facilmente um arquivo de modelagem e ajustá-lo às suas necessidades.
+
+Se você estiver escrevendo um modelo totalmente novo, pode ser mais fácil começar do zero. Neste tutorial, mostraremos
+como escrever um modelo customizado e sua configuração para que possa ser usado com Transformers, e como você pode compartilhá-lo
+com a comunidade (com o código em que se baseia) para que qualquer pessoa possa usá-lo, mesmo se não estiver presente na biblioteca 🤗 Transformers.
+
+Ilustraremos tudo isso em um modelo ResNet, envolvendo a classe ResNet do
+[biblioteca timm](https://github.com/rwightman/pytorch-image-models) em um [`PreTrainedModel`].
+
+## Escrevendo uma configuração customizada
+
+Antes de mergulharmos no modelo, vamos primeiro escrever sua configuração. A configuração de um modelo é um objeto que
+terá todas as informações necessárias para construir o modelo. Como veremos na próxima seção, o modelo só pode
+ter um `config` para ser inicializado, então realmente precisamos que esse objeto seja o mais completo possível.
+
+Em nosso exemplo, pegaremos alguns argumentos da classe ResNet que podemos querer ajustar. Diferentes
+configurações nos dará os diferentes tipos de ResNets que são possíveis. Em seguida, apenas armazenamos esses argumentos,
+após verificar a validade de alguns deles.
+
+```python
+from transformers import PretrainedConfig
+from typing import List
+
+
+class ResnetConfig(PretrainedConfig):
+ model_type = "resnet"
+
+ def __init__(
+ self,
+ block_type="bottleneck",
+ layers: List[int] = [3, 4, 6, 3],
+ num_classes: int = 1000,
+ input_channels: int = 3,
+ cardinality: int = 1,
+ base_width: int = 64,
+ stem_width: int = 64,
+ stem_type: str = "",
+ avg_down: bool = False,
+ **kwargs,
+ ):
+ if block_type not in ["basic", "bottleneck"]:
+ raise ValueError(f"`block_type` must be 'basic' or bottleneck', got {block_type}.")
+ if stem_type not in ["", "deep", "deep-tiered"]:
+ raise ValueError(f"`stem_type` must be '', 'deep' or 'deep-tiered', got {stem_type}.")
+
+ self.block_type = block_type
+ self.layers = layers
+ self.num_classes = num_classes
+ self.input_channels = input_channels
+ self.cardinality = cardinality
+ self.base_width = base_width
+ self.stem_width = stem_width
+ self.stem_type = stem_type
+ self.avg_down = avg_down
+ super().__init__(**kwargs)
+```
+
+As três coisas importantes a serem lembradas ao escrever sua própria configuração são:
+- você tem que herdar de `PretrainedConfig`,
+- o `__init__` do seu `PretrainedConfig` deve aceitar quaisquer kwargs,
+- esses `kwargs` precisam ser passados para a superclasse `__init__`.
+
+A herança é para garantir que você obtenha todas as funcionalidades da biblioteca 🤗 Transformers, enquanto as outras duas
+restrições vêm do fato de um `PretrainedConfig` ter mais campos do que os que você está configurando. Ao recarregar um
+config com o método `from_pretrained`, esses campos precisam ser aceitos pelo seu config e então enviados para a
+superclasse.
+
+Definir um `model_type` para sua configuração (aqui `model_type="resnet"`) não é obrigatório, a menos que você queira
+registrar seu modelo com as classes automáticas (veja a última seção).
+
+Com isso feito, você pode facilmente criar e salvar sua configuração como faria com qualquer outra configuração de modelo da
+biblioteca. Aqui está como podemos criar uma configuração resnet50d e salvá-la:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d_config.save_pretrained("custom-resnet")
+```
+
+Isso salvará um arquivo chamado `config.json` dentro da pasta `custom-resnet`. Você pode então recarregar sua configuração com o
+método `from_pretrained`:
+
+```py
+resnet50d_config = ResnetConfig.from_pretrained("custom-resnet")
+```
+
+Você também pode usar qualquer outro método da classe [`PretrainedConfig`], como [`~PretrainedConfig.push_to_hub`] para
+carregar diretamente sua configuração para o Hub.
+
+## Escrevendo um modelo customizado
+
+Agora que temos nossa configuração ResNet, podemos continuar escrevendo o modelo. Na verdade, escreveremos dois: um que
+extrai os recursos ocultos de um lote de imagens (como [`BertModel`]) e um que é adequado para classificação de imagem
+(como [`BertForSequenceClassification`]).
+
+Como mencionamos antes, escreveremos apenas um wrapper solto do modelo para mantê-lo simples para este exemplo. A única
+coisa que precisamos fazer antes de escrever esta classe é um mapa entre os tipos de bloco e as classes de bloco reais. Então o
+modelo é definido a partir da configuração passando tudo para a classe `ResNet`:
+
+```py
+from transformers import PreTrainedModel
+from timm.models.resnet import BasicBlock, Bottleneck, ResNet
+from .configuration_resnet import ResnetConfig
+
+
+BLOCK_MAPPING = {"basic": BasicBlock, "bottleneck": Bottleneck}
+
+
+class ResnetModel(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor):
+ return self.model.forward_features(tensor)
+```
+
+Para o modelo que irá classificar as imagens, vamos apenas alterar o método forward:
+
+```py
+import torch
+
+
+class ResnetModelForImageClassification(PreTrainedModel):
+ config_class = ResnetConfig
+
+ def __init__(self, config):
+ super().__init__(config)
+ block_layer = BLOCK_MAPPING[config.block_type]
+ self.model = ResNet(
+ block_layer,
+ config.layers,
+ num_classes=config.num_classes,
+ in_chans=config.input_channels,
+ cardinality=config.cardinality,
+ base_width=config.base_width,
+ stem_width=config.stem_width,
+ stem_type=config.stem_type,
+ avg_down=config.avg_down,
+ )
+
+ def forward(self, tensor, labels=None):
+ logits = self.model(tensor)
+ if labels is not None:
+ loss = torch.nn.functional.cross_entropy(logits, labels)
+ return {"loss": loss, "logits": logits}
+ return {"logits": logits}
+```
+
+Em ambos os casos, observe como herdamos de `PreTrainedModel` e chamamos a inicialização da superclasse com o `config`
+(um pouco parecido quando você escreve um `torch.nn.Module`). A linha que define o `config_class` não é obrigatória, a menos que
+você deseje registrar seu modelo com as classes automáticas (consulte a última seção).
+
+
+
+Se o seu modelo for muito semelhante a um modelo dentro da biblioteca, você poderá reutilizar a mesma configuração desse modelo.
+
+
+
+Você pode fazer com que seu modelo retorne o que você quiser,porém retornando um dicionário como fizemos para
+`ResnetModelForImageClassification`, com a função de perda incluída quando os rótulos são passados, vai tornar seu modelo diretamente
+utilizável dentro da classe [`Trainer`]. Você pode usar outro formato de saída, desde que esteja planejando usar seu próprio
+laço de treinamento ou outra biblioteca para treinamento.
+
+Agora que temos nossa classe do modelo, vamos criar uma:
+
+```py
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+```
+
+Novamente, você pode usar qualquer um dos métodos do [`PreTrainedModel`], como [`~PreTrainedModel.save_pretrained`] ou
+[`~PreTrainedModel.push_to_hub`]. Usaremos o segundo na próxima seção e veremos como enviar os pesos e
+o código do nosso modelo. Mas primeiro, vamos carregar alguns pesos pré-treinados dentro do nosso modelo.
+
+Em seu próprio caso de uso, você provavelmente estará treinando seu modelo customizado em seus próprios dados. Para este tutorial ser rápido,
+usaremos a versão pré-treinada do resnet50d. Como nosso modelo é apenas um wrapper em torno dele, será
+fácil de transferir esses pesos:
+
+```py
+import timm
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+Agora vamos ver como ter certeza de que quando fazemos [`~PreTrainedModel.save_pretrained`] ou [`~PreTrainedModel.push_to_hub`], o
+código do modelo é salvo.
+
+## Enviando o código para o Hub
+
+
+
+Esta API é experimental e pode ter algumas pequenas alterações nas próximas versões.
+
+
+
+Primeiro, certifique-se de que seu modelo esteja totalmente definido em um arquivo `.py`. Ele pode contar com importações relativas para alguns outros arquivos
+desde que todos os arquivos estejam no mesmo diretório (ainda não suportamos submódulos para este recurso). Para o nosso exemplo,
+vamos definir um arquivo `modeling_resnet.py` e um arquivo `configuration_resnet.py` em uma pasta no
+diretório de trabalho atual chamado `resnet_model`. O arquivo de configuração contém o código para `ResnetConfig` e o arquivo de modelagem
+contém o código do `ResnetModel` e `ResnetModelForImageClassification`.
+
+```
+.
+└── resnet_model
+ ├── __init__.py
+ ├── configuration_resnet.py
+ └── modeling_resnet.py
+```
+
+O `__init__.py` pode estar vazio, apenas está lá para que o Python detecte que o `resnet_model` possa ser usado como um módulo.
+
+
+
+Se estiver copiando arquivos de modelagem da biblioteca, você precisará substituir todas as importações relativas na parte superior do arquivo
+para importar do pacote `transformers`.
+
+
+
+Observe que você pode reutilizar (ou subclasse) uma configuração/modelo existente.
+
+Para compartilhar seu modelo com a comunidade, siga estas etapas: primeiro importe o modelo ResNet e a configuração do
+arquivos criados:
+
+```py
+from resnet_model.configuration_resnet import ResnetConfig
+from resnet_model.modeling_resnet import ResnetModel, ResnetModelForImageClassification
+```
+
+Então você tem que dizer à biblioteca que deseja copiar os arquivos de código desses objetos ao usar o `save_pretrained`
+e registrá-los corretamente com uma determinada classe automáticas (especialmente para modelos), basta executar:
+
+```py
+ResnetConfig.register_for_auto_class()
+ResnetModel.register_for_auto_class("AutoModel")
+ResnetModelForImageClassification.register_for_auto_class("AutoModelForImageClassification")
+```
+
+Observe que não há necessidade de especificar uma classe automática para a configuração (há apenas uma classe automática,
+[`AutoConfig`]), mas é diferente para os modelos. Seu modelo customizado pode ser adequado para muitas tarefas diferentes, então você
+tem que especificar qual das classes automáticas é a correta para o seu modelo.
+
+Em seguida, vamos criar a configuração e os modelos como fizemos antes:
+
+```py
+resnet50d_config = ResnetConfig(block_type="bottleneck", stem_width=32, stem_type="deep", avg_down=True)
+resnet50d = ResnetModelForImageClassification(resnet50d_config)
+
+pretrained_model = timm.create_model("resnet50d", pretrained=True)
+resnet50d.model.load_state_dict(pretrained_model.state_dict())
+```
+
+Agora para enviar o modelo para o Hub, certifique-se de estar logado. Ou execute no seu terminal:
+
+```bash
+huggingface-cli login
+```
+
+ou a partir do notebook:
+
+```py
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+Você pode então enviar para seu próprio namespace (ou uma organização da qual você é membro) assim:
+
+
+```py
+resnet50d.push_to_hub("custom-resnet50d")
+```
+
+Além dos pesos do modelo e da configuração no formato json, isso também copiou o modelo e
+configuração `.py` na pasta `custom-resnet50d` e carregou o resultado para o Hub. Você pode conferir o resultado
+neste [repositório de modelos](https://huggingface.co/sgugger/custom-resnet50d).
+
+Consulte o [tutorial de compartilhamento](model_sharing) para obter mais informações sobre o método push_to_hub.
+
+## Usando um modelo com código customizado
+
+Você pode usar qualquer configuração, modelo ou tokenizador com arquivos de código customizados em seu repositório com as classes automáticas e
+o método `from_pretrained`. Todos os arquivos e códigos carregados no Hub são verificados quanto a malware (consulte a documentação de [Segurança do Hub](https://huggingface.co/docs/hub/security#malware-scanning) para obter mais informações), mas você ainda deve
+revisar o código do modelo e o autor para evitar a execução de código malicioso em sua máquina. Defina `trust_remote_code=True` para usar
+um modelo com código customizado:
+
+```py
+from transformers import AutoModelForImageClassification
+
+model = AutoModelForImageClassification.from_pretrained("sgugger/custom-resnet50d", trust_remote_code=True)
+```
+
+Também é fortemente recomendado passar um hash de confirmação como uma `revisão` para garantir que o autor dos modelos não
+atualize o código com novas linhas maliciosas (a menos que você confie totalmente nos autores dos modelos).
+
+
+```py
+commit_hash = "ed94a7c6247d8aedce4647f00f20de6875b5b292"
+model = AutoModelForImageClassification.from_pretrained(
+ "sgugger/custom-resnet50d", trust_remote_code=True, revision=commit_hash
+)
+```
+
+Observe que ao navegar no histórico de commits do repositório do modelo no Hub, há um botão para copiar facilmente o commit
+hash de qualquer commit.
+
+## Registrando um modelo com código customizado para as classes automáticas
+
+Se você estiver escrevendo uma biblioteca que estende 🤗 Transformers, talvez queira estender as classes automáticas para incluir seus próprios
+modelos. Isso é diferente de enviar o código para o Hub no sentido de que os usuários precisarão importar sua biblioteca para
+obter os modelos customizados (ao contrário de baixar automaticamente o código do modelo do Hub).
+
+Desde que sua configuração tenha um atributo `model_type` diferente dos tipos de modelo existentes e que as classes do seu modelo
+tenha os atributos `config_class` corretos, você pode simplesmente adicioná-los às classes automáticas assim:
+
+```py
+from transformers import AutoConfig, AutoModel, AutoModelForImageClassification
+
+AutoConfig.register("resnet", ResnetConfig)
+AutoModel.register(ResnetConfig, ResnetModel)
+AutoModelForImageClassification.register(ResnetConfig, ResnetModelForImageClassification)
+```
+
+Observe que o primeiro argumento usado ao registrar sua configuração customizada para [`AutoConfig`] precisa corresponder ao `model_type`
+de sua configuração customizada. E o primeiro argumento usado ao registrar seus modelos customizados, para qualquer necessidade de classe de modelo automático
+deve corresponder ao `config_class` desses modelos.
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/fast_tokenizers.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/fast_tokenizers.md
new file mode 100644
index 0000000000000000000000000000000000000000..ea1da8a61571f1a4969e1b7751de08a8b0ca40ea
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/fast_tokenizers.md
@@ -0,0 +1,66 @@
+
+
+# Usando os Tokenizers do 🤗 Tokenizers
+
+O [`PreTrainedTokenizerFast`] depende da biblioteca [🤗 Tokenizers](https://huggingface.co/docs/tokenizers). O Tokenizer obtido da biblioteca 🤗 Tokenizers pode ser carregado facilmente pelo 🤗 Transformers.
+
+Antes de entrar nos detalhes, vamos começar criando um tokenizer fictício em algumas linhas:
+
+```python
+>>> from tokenizers import Tokenizer
+>>> from tokenizers.models import BPE
+>>> from tokenizers.trainers import BpeTrainer
+>>> from tokenizers.pre_tokenizers import Whitespace
+
+>>> tokenizer = Tokenizer(BPE(unk_token="[UNK]"))
+>>> trainer = BpeTrainer(special_tokens=["[UNK]", "[CLS]", "[SEP]", "[PAD]", "[MASK]"])
+
+>>> tokenizer.pre_tokenizer = Whitespace()
+>>> files = [...]
+>>> tokenizer.train(files, trainer)
+```
+
+Agora temos um tokenizer treinado nos arquivos que foram definidos. Nós podemos continuar usando nessa execução ou salvar em um arquivo JSON para re-utilizar no futuro.
+
+## Carregando diretamente de um objeto tokenizer
+
+Vamos ver como aproveitar esse objeto tokenizer na biblioteca 🤗 Transformers. A classe [`PreTrainedTokenizerFast`] permite uma instanciação fácil, aceitando o objeto *tokenizer* instanciado como um argumento:
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_object=tokenizer)
+```
+Esse objeto pode ser utilizado com todos os métodos compartilhados pelos tokenizers dos 🤗 Transformers! Vá para [a página do tokenizer](main_classes/tokenizer) para mais informações.
+
+## Carregando de um arquivo JSON
+
+Para carregar um tokenizer de um arquivo JSON vamos primeiro começar salvando nosso tokenizer:
+
+```python
+>>> tokenizer.save("tokenizer.json")
+```
+
+A pasta para qual salvamos esse arquivo pode ser passada para o método de inicialização do [`PreTrainedTokenizerFast`] usando o `tokenizer_file` parâmetro:
+
+```python
+>>> from transformers import PreTrainedTokenizerFast
+
+>>> fast_tokenizer = PreTrainedTokenizerFast(tokenizer_file="tokenizer.json")
+```
+
+Esse objeto pode ser utilizado com todos os métodos compartilhados pelos tokenizers dos 🤗 Transformers! Vá para [a página do tokenizer](main_classes/tokenizer) para mais informações.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/index.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/index.md
new file mode 100644
index 0000000000000000000000000000000000000000..18dbcbc06b8048511655b0bbfa5ab75a199696b2
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/index.md
@@ -0,0 +1,296 @@
+
+
+# 🤗 Transformers
+
+
+Estado da Arte para Aprendizado de Máquina em PyTorch, TensorFlow e JAX.
+O 🤗 Transformers disponibiliza APIs para facilmente baixar e treinar modelos pré-treinados de última geração.
+O uso de modelos pré-treinados pode diminuir os seus custos de computação, a sua pegada de carbono, além de economizar o
+tempo necessário para se treinar um modelo do zero. Os modelos podem ser usados para diversas tarefas:
+
+* 📝 Textos: classificação, extração de informações, perguntas e respostas, resumir, traduzir e gerar textos em mais de 100 idiomas.
+* 🖼 Imagens: classificação, deteção de objetos, e segmentação.
+* 🗣 Audio: reconhecimento de fala e classificação de áudio.
+* 🐙 Multimodal: perguntas tabeladas e respsostas, reconhecimento ótico de charactéres, extração de informação de
+documentos escaneados, classificação de vídeo, perguntas e respostas visuais.
+
+Nossa biblioteca aceita integração contínua entre três das bibliotecas mais populares de aprendizado profundo:
+Our library supports seamless integration between three of the most popular deep learning libraries:
+[PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/) e [JAX](https://jax.readthedocs.io/en/latest/).
+Treine seu modelo em três linhas de código em um framework, e carregue-o para execução em outro.
+
+Cada arquitetura 🤗 Transformers é definida em um módulo individual do Python, para que seja facilmente customizável para pesquisa e experimentos.
+
+## Se você estiver procurando suporte do time da Hugging Face, acesse
+
+
+
+
+
+## Conteúdo
+
+A documentação é dividida em cinco partes:
+ - **INÍCIO** contém um tour rápido de instalação e instruções para te dar um empurrão inicial com os 🤗 Transformers.
+ - **TUTORIAIS** são perfeitos para começar a aprender sobre a nossa biblioteca. Essa seção irá te ajudar a desenvolver
+ habilidades básicas necessárias para usar o 🤗 Transformers.
+ - **GUIAS PRÁTICOS** irão te mostrar como alcançar um certo objetivo, como o fine-tuning de um modelo pré-treinado
+ para modelamento de idioma, ou como criar um cabeçalho personalizado para um modelo.
+ - **GUIAS CONCEITUAIS** te darão mais discussões e explicações dos conceitos fundamentais e idéias por trás dos modelos,
+ tarefas e da filosofia de design por trás do 🤗 Transformers.
+ - **API** descreve o funcionamento de cada classe e função, agrupada em:
+
+ - **CLASSES PRINCIPAIS** para as classes que expõe as APIs importantes da biblioteca.
+ - **MODELOS** para as classes e funções relacionadas à cada modelo implementado na biblioteca.
+ - **AUXILIARES INTERNOS** para as classes e funções usadas internamente.
+
+Atualmente a biblioteca contém implementações do PyTorch, TensorFlow e JAX, pesos para modelos pré-treinados e scripts de uso e conversão de utilidades para os seguintes modelos:
+
+### Modelos atuais
+
+
+
+1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
+1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
+1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
+1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
+1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
+1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
+1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
+1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499) by Adrian de Wynter and Daniel J. Perry.
+1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
+1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
+1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
+1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
+1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
+1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
+1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
+1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
+1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
+1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
+1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
+1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) and a German version of DistilBERT.
+1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
+1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+1. **[EfficientNet](model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://arxiv.org/abs/1905.11946) by Mingxing Tan and Quoc V. Le.
+1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
+1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
+1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
+1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
+1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
+1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
+1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
+1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
+1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released in the repository [tanreinama/GPTSAN](https://github.com/tanreinama/GPTSAN/blob/main/report/model.md) by Toshiyuki Sakamoto(tanreinama).
+1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
+1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
+1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
+1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
+1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
+1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
+1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
+1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
+1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490) by Hao Tan and Mohit Bansal.
+1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
+1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
+1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
+1. **[MBart](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+1. **[MBart-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
+1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
+1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
+1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
+1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
+1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
+1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
+1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
+1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
+1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
+1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://arxiv.org/abs/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
+1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
+1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
+1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
+1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
+1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
+1. **[SqueezeBert](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
+1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
+1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
+1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
+1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
+1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
+1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
+1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://arxiv.org/abs/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
+1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
+1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
+1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
+1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
+1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
+1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
+1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291) by Guillaume Lample and Alexis Conneau.
+1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
+1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
+1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
+1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
+1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
+1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
+
+
+### Frameworks aceitos
+
+A tabela abaixo representa a lista de suporte na biblioteca para cada um dos seguintes modelos, caso tenham um tokenizer
+do Python (chamado de "slow"), ou um tokenizer construído em cima da biblioteca 🤗 Tokenizers (chamado de "fast"). Além
+disso, são diferenciados pelo suporte em diferentes frameworks: JAX (por meio do Flax); PyTorch; e/ou Tensorflow.
+
+
+
+| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:---------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBirdPegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Canine | ✅ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNext | ❌ | ❌ | ✅ | ✅ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecVision | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MegatronBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| mT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Nystromformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Realm | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ❌ | ✅ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| SegFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Swin | ❌ | ❌ | ✅ | ❌ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TAPEX | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| VisualBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ❌ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLMProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/installation.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/installation.md
new file mode 100644
index 0000000000000000000000000000000000000000..f548736589ac0d81bc7ebe2d73d60652ce03040b
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/installation.md
@@ -0,0 +1,262 @@
+
+
+# Guia de Instalação
+
+Neste guia poderá encontrar informações para a instalação do 🤗 Transformers para qualquer biblioteca de
+Machine Learning com a qual esteja a trabalhar. Além disso, poderá encontrar informações sobre como gerar cachês e
+configurar o 🤗 Transformers para execução em modo offline (opcional).
+
+🤗 Transformers foi testado com Python 3.6+, PyTorch 1.1.0+, TensorFlow 2.0+, e Flax. Para instalar a biblioteca de
+deep learning com que deseja trabalhar, siga as instruções correspondentes listadas a seguir:
+
+* [PyTorch](https://pytorch.org/get-started/locally/)
+* [TensorFlow 2.0](https://www.tensorflow.org/install/pip)
+* [Flax](https://flax.readthedocs.io/en/latest/)
+
+## Instalação pelo Pip
+
+É sugerido instalar o 🤗 Transformers num [ambiente virtual](https://docs.python.org/3/library/venv.html). Se precisar
+de mais informações sobre ambientes virtuais em Python, consulte este [guia](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/).
+Um ambiente virtual facilitará a manipulação e organização de projetos e evita problemas de compatibilidade entre dependências.
+
+Comece criando um ambiente virtual no diretório do seu projeto:
+
+```bash
+python -m venv .env
+```
+
+E para ativar o ambiente virtual:
+
+```bash
+source .env/bin/activate
+```
+
+Agora É possível instalar o 🤗 Transformers com o comando a seguir:
+
+```bash
+pip install transformers
+```
+
+Somente para a CPU, é possível instalar o 🤗 Transformers e a biblioteca de deep learning respectiva apenas numa linha.
+
+Por exemplo, para instalar o 🤗 Transformers e o PyTorch, digite:
+
+```bash
+pip install transformers[torch]
+```
+
+🤗 Transformers e TensorFlow 2.0:
+
+```bash
+pip install transformers[tf-cpu]
+```
+
+🤗 Transformers e Flax:
+
+```bash
+pip install transformers[flax]
+```
+
+Por último, verifique se o 🤗 Transformers foi instalado com sucesso usando o seguinte comando para baixar um modelo pré-treinado:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('we love you'))"
+```
+
+Em seguida, imprima um rótulo e sua pontuação:
+
+```bash
+[{'label': 'POSITIVE', 'score': 0.9998704791069031}]
+```
+
+## Instalação usando a fonte
+
+Para instalar o 🤗 Transformers a partir da fonte use o seguinte comando:
+
+```bash
+pip install git+https://github.com/huggingface/transformers
+```
+
+O comando acima instalará a versão `master` mais atual em vez da última versão estável. A versão `master` é útil para
+utilizar os últimos updates contidos em 🤗 Transformers. Por exemplo, um erro recente pode ter sido corrigido somente
+após a última versão estável, antes que houvesse um novo lançamento. No entanto, há a possibilidade que a versão `master` não esteja estável.
+A equipa trata de mantér a versão `master` operacional e a maioria dos erros são resolvidos em poucas horas ou dias.
+Se encontrar quaisquer problemas, por favor abra um [Issue](https://github.com/huggingface/transformers/issues) para que o
+mesmo possa ser corrigido o mais rápido possível.
+
+Verifique que o 🤗 Transformers está instalado corretamente usando o seguinte comando:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('I love you'))"
+```
+
+## Instalação editável
+
+Uma instalação editável será necessária caso desejas um dos seguintes:
+* Usar a versão `master` do código fonte.
+* Contribuir ao 🤗 Transformers e precisa testar mudanças ao código.
+
+Para tal, clone o repositório e instale o 🤗 Transformers com os seguintes comandos:
+
+```bash
+git clone https://github.com/huggingface/transformers.git
+cd transformers
+pip install -e .
+```
+
+Estes comandos vão ligar o diretório para o qual foi clonado o repositório ao caminho de bibliotecas do Python.
+O Python agora buscará dentro dos arquivos que foram clonados além dos caminhos normais da biblioteca.
+Por exemplo, se os pacotes do Python se encontram instalados no caminho `~/anaconda3/envs/main/lib/python3.7/site-packages/`,
+o Python também buscará módulos no diretório onde clonamos o repositório `~/transformers/`.
+
+
+
+É necessário manter o diretório `transformers` se desejas continuar usando a biblioteca.
+
+
+
+Assim, É possível atualizar sua cópia local para com a última versão do 🤗 Transformers com o seguinte comando:
+
+```bash
+cd ~/transformers/
+git pull
+```
+
+O ambiente de Python que foi criado para a instalação do 🤗 Transformers encontrará a versão `master` em execuções seguintes.
+
+## Instalação usando o Conda
+
+É possível instalar o 🤗 Transformers a partir do canal conda `conda-forge` com o seguinte comando:
+
+```bash
+conda install conda-forge::transformers
+```
+
+## Configuração do Cachê
+
+Os modelos pré-treinados são baixados e armazenados no cachê local, encontrado em `~/.cache/huggingface/transformers/`.
+Este é o diretório padrão determinado pela variável `TRANSFORMERS_CACHE` dentro do shell.
+No Windows, este diretório pré-definido é dado por `C:\Users\username\.cache\huggingface\transformers`.
+É possível mudar as variáveis dentro do shell em ordem de prioridade para especificar um diretório de cachê diferente:
+
+1. Variável de ambiente do shell (por padrão): `TRANSFORMERS_CACHE`.
+2. Variável de ambiente do shell:`HF_HOME` + `transformers/`.
+3. Variável de ambiente do shell: `XDG_CACHE_HOME` + `/huggingface/transformers`.
+
+
+
+ O 🤗 Transformers usará as variáveis de ambiente do shell `PYTORCH_TRANSFORMERS_CACHE` ou `PYTORCH_PRETRAINED_BERT_CACHE`
+ se estiver vindo de uma versão anterior da biblioteca que tenha configurado essas variáveis de ambiente, a menos que
+ você especifique a variável de ambiente do shell `TRANSFORMERS_CACHE`.
+
+
+
+
+## Modo Offline
+
+O 🤗 Transformers também pode ser executado num ambiente de firewall ou fora da rede (offline) usando arquivos locais.
+Para tal, configure a variável de ambiente de modo que `HF_HUB_OFFLINE=1`.
+
+
+
+Você pode adicionar o [🤗 Datasets](https://huggingface.co/docs/datasets/) ao pipeline de treinamento offline declarando
+ a variável de ambiente `HF_DATASETS_OFFLINE=1`.
+
+
+
+Segue um exemplo de execução do programa numa rede padrão com firewall para instâncias externas, usando o seguinte comando:
+
+```bash
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+Execute esse mesmo programa numa instância offline com o seguinte comando:
+
+```bash
+HF_DATASETS_OFFLINE=1 HF_HUB_OFFLINE=1 \
+python examples/pytorch/translation/run_translation.py --model_name_or_path google-t5/t5-small --dataset_name wmt16 --dataset_config ro-en ...
+```
+
+O script agora deve ser executado sem travar ou expirar, pois procurará apenas por arquivos locais.
+
+### Obtendo modelos e tokenizers para uso offline
+
+Outra opção para usar o 🤗 Transformers offline é baixar os arquivos antes e depois apontar para o caminho local onde estão localizados. Existem três maneiras de fazer isso:
+
+* Baixe um arquivo por meio da interface de usuário do [Model Hub](https://huggingface.co/models) clicando no ícone ↓.
+
+ 
+
+
+* Use o pipeline do [`PreTrainedModel.from_pretrained`] e [`PreTrainedModel.save_pretrained`]:
+ 1. Baixa os arquivos previamente com [`PreTrainedModel.from_pretrained`]:
+
+ ```py
+ >>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("bigscience/T0_3B")
+ >>> model = AutoModelForSeq2SeqLM.from_pretrained("bigscience/T0_3B")
+ ```
+
+
+ 2. Salve os arquivos em um diretório específico com [`PreTrainedModel.save_pretrained`]:
+
+ ```py
+ >>> tokenizer.save_pretrained("./your/path/bigscience_t0")
+ >>> model.save_pretrained("./your/path/bigscience_t0")
+ ```
+
+ 3. Quando estiver offline, acesse os arquivos com [`PreTrainedModel.from_pretrained`] do diretório especificado:
+
+ ```py
+ >>> tokenizer = AutoTokenizer.from_pretrained("./your/path/bigscience_t0")
+ >>> model = AutoModel.from_pretrained("./your/path/bigscience_t0")
+ ```
+
+* Baixando arquivos programaticamente com a biblioteca [huggingface_hub](https://github.com/huggingface/huggingface_hub/tree/main/src/huggingface_hub):
+
+ 1. Instale a biblioteca [huggingface_hub](https://github.com/huggingface/huggingface_hub/tree/main/src/huggingface_hub) em seu ambiente virtual:
+
+ ```bash
+ python -m pip install huggingface_hub
+ ```
+
+ 2. Utiliza a função [`hf_hub_download`](https://huggingface.co/docs/hub/adding-a-library#download-files-from-the-hub) para baixar um arquivo para um caminho específico. Por exemplo, o comando a seguir baixará o arquivo `config.json` para o modelo [T0](https://huggingface.co/bigscience/T0_3B) no caminho desejado:
+
+ ```py
+ >>> from huggingface_hub import hf_hub_download
+
+ >>> hf_hub_download(repo_id="bigscience/T0_3B", filename="config.json", cache_dir="./your/path/bigscience_t0")
+ ```
+
+Depois que o arquivo for baixado e armazenado no cachê local, especifique seu caminho local para carregá-lo e usá-lo:
+
+```py
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("./your/path/bigscience_t0/config.json")
+```
+
+
+
+Para obter mais detalhes sobre como baixar arquivos armazenados no Hub, consulte a seção [How to download files from the Hub](https://huggingface.co/docs/hub/how-to-downstream).
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/multilingual.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/multilingual.md
new file mode 100644
index 0000000000000000000000000000000000000000..5515c6a922a7019b60f7b8e9baf0eb1ab0f84c43
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/multilingual.md
@@ -0,0 +1,195 @@
+
+
+# Modelos multilinguísticos para inferência
+
+[[open-in-colab]]
+
+Existem vários modelos multilinguísticos no 🤗 Transformers e seus usos para inferência diferem dos modelos monolíngues.
+No entanto, nem *todos* os usos dos modelos multilíngues são tão diferentes.
+Alguns modelos, como o [google-bert/bert-base-multilingual-uncased](https://huggingface.co/google-bert/bert-base-multilingual-uncased),
+podem ser usados como se fossem monolíngues. Este guia irá te ajudar a usar modelos multilíngues cujo uso difere
+para o propósito de inferência.
+
+## XLM
+
+O XLM tem dez checkpoints diferentes dos quais apenas um é monolíngue.
+Os nove checkpoints restantes do modelo são subdivididos em duas categorias:
+checkpoints que usam de language embeddings e os que não.
+
+### XLM com language embeddings
+
+Os seguintes modelos de XLM usam language embeddings para especificar a linguagem utilizada para a inferência.
+
+- `FacebookAI/xlm-mlm-ende-1024` (Masked language modeling, English-German)
+- `FacebookAI/xlm-mlm-enfr-1024` (Masked language modeling, English-French)
+- `FacebookAI/xlm-mlm-enro-1024` (Masked language modeling, English-Romanian)
+- `FacebookAI/xlm-mlm-xnli15-1024` (Masked language modeling, XNLI languages)
+- `FacebookAI/xlm-mlm-tlm-xnli15-1024` (Masked language modeling + translation, XNLI languages)
+- `FacebookAI/xlm-clm-enfr-1024` (Causal language modeling, English-French)
+- `FacebookAI/xlm-clm-ende-1024` (Causal language modeling, English-German)
+
+Os language embeddings são representados por um tensor de mesma dimensão que os `input_ids` passados ao modelo.
+Os valores destes tensores dependem do idioma utilizado e se identificam pelos atributos `lang2id` e `id2lang` do tokenizador.
+
+Neste exemplo, carregamos o checkpoint `FacebookAI/xlm-clm-enfr-1024`(Causal language modeling, English-French):
+
+```py
+>>> import torch
+>>> from transformers import XLMTokenizer, XLMWithLMHeadModel
+
+>>> tokenizer = XLMTokenizer.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+>>> model = XLMWithLMHeadModel.from_pretrained("FacebookAI/xlm-clm-enfr-1024")
+```
+
+O atributo `lang2id` do tokenizador mostra os idiomas deste modelo e seus ids:
+
+```py
+>>> print(tokenizer.lang2id)
+{'en': 0, 'fr': 1}
+```
+
+Em seguida, cria-se um input de exemplo:
+
+```py
+>>> input_ids = torch.tensor([tokenizer.encode("Wikipedia was used to")]) # batch size of 1
+```
+
+Estabelece-se o id do idioma, por exemplo `"en"`, e utiliza-se o mesmo para definir a language embedding.
+A language embedding é um tensor preenchido com `0`, que é o id de idioma para o inglês.
+Este tensor deve ser do mesmo tamanho que os `input_ids`.
+
+```py
+>>> language_id = tokenizer.lang2id["en"] # 0
+>>> langs = torch.tensor([language_id] * input_ids.shape[1]) # torch.tensor([0, 0, 0, ..., 0])
+
+>>> # We reshape it to be of size (batch_size, sequence_length)
+>>> langs = langs.view(1, -1) # is now of shape [1, sequence_length] (we have a batch size of 1)
+```
+
+Agora você pode passar os `input_ids` e a language embedding ao modelo:
+
+```py
+>>> outputs = model(input_ids, langs=langs)
+```
+
+O script [run_generation.py](https://github.com/huggingface/transformers/tree/master/examples/pytorch/text-generation/run_generation.py) pode gerar um texto com language embeddings utilizando os checkpoints `xlm-clm`.
+
+### XLM sem language embeddings
+
+Os seguintes modelos XLM não requerem o uso de language embeddings durante a inferência:
+
+- `FacebookAI/xlm-mlm-17-1280` (Modelagem de linguagem com máscara, 17 idiomas)
+- `FacebookAI/xlm-mlm-100-1280` (Modelagem de linguagem com máscara, 100 idiomas)
+
+Estes modelos são utilizados para representações genéricas de frase diferentemente dos checkpoints XLM anteriores.
+
+## BERT
+
+Os seguintes modelos do BERT podem ser utilizados para tarefas multilinguísticas:
+
+- `google-bert/bert-base-multilingual-uncased` (Modelagem de linguagem com máscara + Previsão de frases, 102 idiomas)
+- `google-bert/bert-base-multilingual-cased` (Modelagem de linguagem com máscara + Previsão de frases, 104 idiomas)
+
+Estes modelos não requerem language embeddings durante a inferência. Devem identificar a linguagem a partir
+do contexto e realizar a inferência em sequência.
+
+## XLM-RoBERTa
+
+Os seguintes modelos do XLM-RoBERTa podem ser utilizados para tarefas multilinguísticas:
+
+- `FacebookAI/xlm-roberta-base` (Modelagem de linguagem com máscara, 100 idiomas)
+- `FacebookAI/xlm-roberta-large` Modelagem de linguagem com máscara, 100 idiomas)
+
+O XLM-RoBERTa foi treinado com 2,5 TB de dados do CommonCrawl recém-criados e testados em 100 idiomas.
+Proporciona fortes vantagens sobre os modelos multilinguísticos publicados anteriormente como o mBERT e o XLM em tarefas
+subsequentes como a classificação, a rotulagem de sequências e à respostas a perguntas.
+
+## M2M100
+
+Os seguintes modelos de M2M100 podem ser utilizados para traduções multilinguísticas:
+
+- `facebook/m2m100_418M` (Tradução)
+- `facebook/m2m100_1.2B` (Tradução)
+
+Neste exemplo, o checkpoint `facebook/m2m100_418M` é carregado para traduzir do mandarim ao inglês. É possível
+estabelecer o idioma de origem no tokenizador:
+
+```py
+>>> from transformers import M2M100ForConditionalGeneration, M2M100Tokenizer
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> chinese_text = "不要插手巫師的事務, 因為他們是微妙的, 很快就會發怒."
+
+>>> tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M", src_lang="zh")
+>>> model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M")
+```
+
+Tokenização do texto:
+
+```py
+>>> encoded_zh = tokenizer(chinese_text, return_tensors="pt")
+```
+
+O M2M100 força o id do idioma de destino como o primeiro token gerado para traduzir ao idioma de destino.
+É definido o `forced_bos_token_id` como `en` no método `generate` para traduzir ao inglês.
+
+```py
+>>> generated_tokens = model.generate(**encoded_zh, forced_bos_token_id=tokenizer.get_lang_id("en"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+'Do not interfere with the matters of the witches, because they are delicate and will soon be angry.'
+```
+
+## MBart
+
+Os seguintes modelos do MBart podem ser utilizados para tradução multilinguística:
+
+- `facebook/mbart-large-50-one-to-many-mmt` (Tradução automática multilinguística de um a vários, 50 idiomas)
+- `facebook/mbart-large-50-many-to-many-mmt` (Tradução automática multilinguística de vários a vários, 50 idiomas)
+- `facebook/mbart-large-50-many-to-one-mmt` (Tradução automática multilinguística vários a um, 50 idiomas)
+- `facebook/mbart-large-50` (Tradução multilinguística, 50 idiomas)
+- `facebook/mbart-large-cc25`
+
+Neste exemplo, carrega-se o checkpoint `facebook/mbart-large-50-many-to-many-mmt` para traduzir do finlandês ao inglês.
+Pode-se definir o idioma de origem no tokenizador:
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+>>> en_text = "Do not meddle in the affairs of wizards, for they are subtle and quick to anger."
+>>> fi_text = "Älä sekaannu velhojen asioihin, sillä ne ovat hienovaraisia ja nopeasti vihaisia."
+
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/mbart-large-50-many-to-many-mmt", src_lang="fi_FI")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
+```
+
+Tokenizando o texto:
+
+```py
+>>> encoded_en = tokenizer(en_text, return_tensors="pt")
+```
+
+O MBart força o id do idioma de destino como o primeiro token gerado para traduzir ao idioma de destino.
+É definido o `forced_bos_token_id` como `en` no método `generate` para traduzir ao inglês.
+
+```py
+>>> generated_tokens = model.generate(**encoded_en, forced_bos_token_id=tokenizer.lang_code_to_id("en_XX"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+"Don't interfere with the wizard's affairs, because they are subtle, will soon get angry."
+```
+
+Se estiver usando o checkpoint `facebook/mbart-large-50-many-to-one-mmt` não será necessário forçar o id do idioma de destino
+como sendo o primeiro token generado, caso contrário a usagem é a mesma.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/pipeline_tutorial.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/pipeline_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..9c0cb3567e72e38c373d60e7fd9813000333eef1
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/pipeline_tutorial.md
@@ -0,0 +1,157 @@
+
+
+# Pipelines para inferência
+
+Um [pipeline] simplifica o uso dos modelos no [Model Hub](https://huggingface.co/models) para a inferência de uma diversidade de tarefas,
+como a geração de texto, a segmentação de imagens e a classificação de áudio.
+Inclusive, se não tem experiência com alguma modalidade específica ou não compreende o código que forma os modelos,
+pode usar eles mesmo assim com o [pipeline]! Este tutorial te ensinará a:
+
+* Utilizar um [`pipeline`] para inferência.
+* Utilizar um tokenizador ou model específico.
+* Utilizar um [`pipeline`] para tarefas de áudio e visão computacional.
+
+
+
+ Acesse a documentação do [`pipeline`] para obter uma lista completa de tarefas possíveis.
+
+
+
+## Uso do pipeline
+
+Mesmo que cada tarefa tenha um [`pipeline`] associado, é mais simples usar a abstração geral do [`pipeline`] que
+contém todos os pipelines das tarefas mais específicas.
+O [`pipeline`] carrega automaticamenta um modelo predeterminado e um tokenizador com capacidade de inferência para sua
+tarefa.
+
+1. Comece carregando um [`pipeline`] e especifique uma tarefa de inferência:
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline(task="text-generation")
+```
+
+2. Passe seu dado de entrada, no caso um texto, ao [`pipeline`]:
+
+```py
+>>> generator("Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone")
+[{'generated_text': 'Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone, Seven for the Iron-priests at the door to the east, and thirteen for the Lord Kings at the end of the mountain'}]
+```
+
+Se tiver mais de uma entrada, passe-a como uma lista:
+
+```py
+>>> generator(
+... [
+... "Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone",
+... "Nine for Mortal Men, doomed to die, One for the Dark Lord on his dark throne",
+... ]
+... )
+```
+
+Qualquer parâmetro adicional para a sua tarefa também pode ser incluído no [`pipeline`]. A tarefa `text-generation` tem um método
+[`~generation.GenerationMixin.generate`] com vários parâmetros para controlar a saída.
+Por exemplo, se quiser gerar mais de uma saída, defina-a no parâmetro `num_return_sequences`:
+
+```py
+>>> generator(
+... "Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone",
+... num_return_sequences=2,
+... )
+```
+
+### Selecionando um modelo e um tokenizador
+
+O [`pipeline`] aceita qualquer modelo do [Model Hub](https://huggingface.co/models). Há rótulos adicionais no Model Hub
+que te permitem filtrar pelo modelo que gostaria de usar para sua tarefa. Uma vez que tiver escolhido o modelo apropriado,
+carregue-o com as classes `AutoModelFor` e [`AutoTokenizer`] correspondentes. Por exemplo, carregue a classe [`AutoModelForCausalLM`]
+para uma tarefa de modelagem de linguagem causal:
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForCausalLM
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilgpt2")
+>>> model = AutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+Crie uma [`pipeline`] para a sua tarefa e especifíque o modelo e o tokenizador que foram carregados:
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline(task="text-generation", model=model, tokenizer=tokenizer)
+```
+
+Passe seu texto de entrada ao [`pipeline`] para gerar algum texto:
+
+```py
+>>> generator("Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone")
+[{'generated_text': 'Three Rings for the Elven-kings under the sky, Seven for the Dwarf-lords in their halls of stone, Seven for the Dragon-lords (for them to rule in a world ruled by their rulers, and all who live within the realm'}]
+```
+
+## Pipeline de audio
+
+A flexibilidade do [`pipeline`] significa que também pode-se extender às tarefas de áudio.
+La flexibilidad de [`pipeline`] significa que también se puede extender a tareas de audio.
+
+Por exemplo, classifiquemos a emoção de um breve fragmento do famoso discurso de John F. Kennedy /home/rzimmerdev/dev/transformers/docs/source/pt/pipeline_tutorial.md
+Encontre um modelo de [audio classification](https://huggingface.co/models?pipeline_tag=audio-classification) para
+reconhecimento de emoções no Model Hub e carregue-o usando o [`pipeline`]:
+
+```py
+>>> from transformers import pipeline
+
+>>> audio_classifier = pipeline(
+... task="audio-classification", model="ehcalabres/wav2vec2-lg-xlsr-en-speech-emotion-recognition"
+... )
+```
+
+Passe o arquivo de áudio ao [`pipeline`]:
+
+```py
+>>> audio_classifier("jfk_moon_speech.wav")
+[{'label': 'calm', 'score': 0.13856211304664612},
+ {'label': 'disgust', 'score': 0.13148026168346405},
+ {'label': 'happy', 'score': 0.12635163962841034},
+ {'label': 'angry', 'score': 0.12439591437578201},
+ {'label': 'fearful', 'score': 0.12404385954141617}]
+```
+
+## Pipeline de visão computacional
+
+Finalmente, utilizar um [`pipeline`] para tarefas de visão é praticamente a mesma coisa.
+Especifique a sua tarefa de visão e passe a sua imagem ao classificador.
+A imagem pode ser um link ou uma rota local à imagem. Por exemplo, que espécie de gato está presente na imagem?
+
+
+
+```py
+>>> from transformers import pipeline
+
+>>> vision_classifier = pipeline(task="image-classification")
+>>> vision_classifier(
+... images="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+... )
+[{'label': 'lynx, catamount', 'score': 0.4403027892112732},
+ {'label': 'cougar, puma, catamount, mountain lion, painter, panther, Felis concolor',
+ 'score': 0.03433405980467796},
+ {'label': 'snow leopard, ounce, Panthera uncia',
+ 'score': 0.032148055732250214},
+ {'label': 'Egyptian cat', 'score': 0.02353910356760025},
+ {'label': 'tiger cat', 'score': 0.023034192621707916}]
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/quicktour.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/quicktour.md
new file mode 100644
index 0000000000000000000000000000000000000000..cc583697b9a65880c13b4aa9604eb3a3c4e3287c
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/quicktour.md
@@ -0,0 +1,399 @@
+
+
+# Tour rápido
+
+[[open-in-colab]]
+
+Comece a trabalhar com 🤗 Transformers! Comece usando [`pipeline`] para rápida inferência e facilmente carregue um modelo pré-treinado e um tokenizer com [AutoClass](./model_doc/auto) para resolver tarefas de texto, visão ou áudio.
+
+
+
+Todos os exemplos de código apresentados na documentação têm um botão no canto superior direito para escolher se você deseja ocultar ou mostrar o código no Pytorch ou no TensorFlow. Caso contrário, é esperado que funcione para ambos back-ends sem nenhuma alteração.
+
+
+
+## Pipeline
+
+[`pipeline`] é a maneira mais fácil de usar um modelo pré-treinado para uma dada tarefa.
+
+
+
+A [`pipeline`] apoia diversas tarefas fora da caixa:
+
+**Texto**:
+* Análise sentimental: classifica a polaridade de um texto.
+* Geração de texto (em Inglês): gera texto a partir de uma entrada.
+* Reconhecimento de entidade mencionada: legenda cada palavra com uma classe que a representa (pessoa, data, local, etc...)
+* Respostas: extrai uma resposta dado algum contexto e uma questão
+* Máscara de preenchimento: preenche o espaço, dado um texto com máscaras de palavras.
+* Sumarização: gera o resumo de um texto longo ou documento.
+* Tradução: traduz texto para outra língua.
+* Extração de características: cria um tensor que representa o texto.
+
+**Imagem**:
+* Classificação de imagens: classifica uma imagem.
+* Segmentação de imagem: classifica cada pixel da imagem.
+* Detecção de objetos: detecta objetos em uma imagem.
+
+**Audio**:
+* Classficação de áudio: legenda um trecho de áudio fornecido.
+* Reconhecimento de fala automático: transcreve audio em texto.
+
+
+
+Para mais detalhes sobre a [`pipeline`] e tarefas associadas, siga a documentação [aqui](./main_classes/pipelines).
+
+
+
+### Uso da pipeline
+
+No exemplo a seguir, você usará [`pipeline`] para análise sentimental.
+
+Instale as seguintes dependências se você ainda não o fez:
+
+
+
+
+```bash
+pip install torch
+```
+
+
+```bash
+pip install tensorflow
+```
+
+
+
+Importe [`pipeline`] e especifique a tarefa que deseja completar:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("sentiment-analysis")
+```
+
+A pipeline baixa and armazena um [modelo pré-treinado](https://huggingface.co/distilbert/distilbert-base-uncased-finetuned-sst-2-english) padrão e tokenizer para análise sentimental. Agora você pode usar `classifier` no texto alvo:
+
+```py
+>>> classifier("We are very happy to show you the 🤗 Transformers library.")
+[{'label': 'POSITIVE', 'score': 0.9998}]
+```
+
+Para mais de uma sentença, passe uma lista para a [`pipeline`], a qual retornará uma lista de dicionários:
+
+```py
+>>> results = classifier(["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."])
+>>> for result in results:
+... print(f"label: {result['label']}, with score: {round(result['score'], 4)}")
+label: POSITIVE, with score: 0.9998
+label: NEGATIVE, with score: 0.5309
+```
+
+A [`pipeline`] também pode iterar sobre um Dataset inteiro. Comece instalando a biblioteca de [🤗 Datasets](https://huggingface.co/docs/datasets/):
+
+```bash
+pip install datasets
+```
+
+Crie uma [`pipeline`] com a tarefa que deseja resolver e o modelo que deseja usar.
+
+```py
+>>> import torch
+>>> from transformers import pipeline
+
+>>> speech_recognizer = pipeline("automatic-speech-recognition", model="facebook/wav2vec2-base-960h")
+```
+
+A seguir, carregue uma base de dados (confira a 🤗 [Iniciação em Datasets](https://huggingface.co/docs/datasets/quickstart) para mais detalhes) que você gostaria de iterar sobre. Por exemplo, vamos carregar o dataset [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14):
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train") # doctest: +IGNORE_RESULT
+```
+
+Precisamos garantir que a taxa de amostragem do conjunto de dados corresponda à taxa de amostragem em que o facebook/wav2vec2-base-960h foi treinado.
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=speech_recognizer.feature_extractor.sampling_rate))
+```
+
+Os arquivos de áudio são carregados e re-amostrados automaticamente ao chamar a coluna `"audio"`.
+Vamos extrair as arrays de formas de onda originais das primeiras 4 amostras e passá-las como uma lista para o pipeline:
+
+```py
+>>> result = speech_recognizer(dataset[:4]["audio"])
+>>> print([d["text"] for d in result])
+['I WOULD LIKE TO SET UP A JOINT ACCOUNT WITH MY PARTNER HOW DO I PROCEED WITH DOING THAT', "FONDERING HOW I'D SET UP A JOIN TO HET WITH MY WIFE AND WHERE THE AP MIGHT BE", "I I'D LIKE TOY SET UP A JOINT ACCOUNT WITH MY PARTNER I'M NOT SEEING THE OPTION TO DO IT ON THE APSO I CALLED IN TO GET SOME HELP CAN I JUST DO IT OVER THE PHONE WITH YOU AND GIVE YOU THE INFORMATION OR SHOULD I DO IT IN THE AP AND I'M MISSING SOMETHING UQUETTE HAD PREFERRED TO JUST DO IT OVER THE PHONE OF POSSIBLE THINGS", 'HOW DO I TURN A JOIN A COUNT']
+```
+
+Para um conjunto de dados maior onde as entradas são maiores (como em fala ou visão), será necessário passar um gerador em vez de uma lista que carregue todas as entradas na memória. Consulte a [documentação do pipeline](./main_classes/pipelines) para mais informações.
+
+### Use outro modelo e tokenizer na pipeline
+
+A [`pipeline`] pode acomodar qualquer modelo do [Model Hub](https://huggingface.co/models), facilitando sua adaptação para outros casos de uso. Por exemplo, se você quiser um modelo capaz de lidar com texto em francês, use as tags no Model Hub para filtrar um modelo apropriado. O principal resultado filtrado retorna um [modelo BERT](https://huggingface.co/nlptown/bert-base-multilingual-uncased-sentiment) bilíngue ajustado para análise de sentimentos. Ótimo, vamos usar este modelo!
+
+```py
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+```
+
+
+
+Use o [`AutoModelForSequenceClassification`] e [`AutoTokenizer`] para carregar o modelo pré-treinado e seu tokenizer associado (mais em `AutoClass` abaixo):
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+Use o [`TFAutoModelForSequenceClassification`] and [`AutoTokenizer`] para carregar o modelo pré-treinado e o tokenizer associado (mais em `TFAutoClass` abaixo):
+
+```py
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+Então você pode especificar o modelo e o tokenizador na [`pipeline`] e aplicar o `classifier` no seu texto alvo:
+
+```py
+>>> classifier = pipeline("sentiment-analysis", model=model, tokenizer=tokenizer)
+>>> classifier("Nous sommes très heureux de vous présenter la bibliothèque 🤗 Transformers.")
+[{'label': '5 stars', 'score': 0.7273}]
+```
+
+Se você não conseguir achar um modelo para o seu caso de uso, precisará usar fine-tune em um modelo pré-treinado nos seus dados. Veja nosso [tutorial de fine-tuning](./training) para descobrir como. Finalmente, depois que você tiver usado esse processo em seu modelo, considere compartilhá-lo conosco (veja o tutorial [aqui](./model_sharing)) na plataforma Model Hub afim de democratizar NLP! 🤗
+
+## AutoClass
+
+
+
+Por baixo dos panos, as classes [`AutoModelForSequenceClassification`] e [`AutoTokenizer`] trabalham juntas para fortificar o [`pipeline`]. Um [AutoClass](./model_doc/auto) é um atalho que automaticamente recupera a arquitetura de um modelo pré-treinado a partir de seu nome ou caminho. Basta selecionar a `AutoClass` apropriada para sua tarefa e seu tokenizer associado com [`AutoTokenizer`].
+
+Vamos voltar ao nosso exemplo e ver como você pode usar a `AutoClass` para replicar os resultados do [`pipeline`].
+
+### AutoTokenizer
+
+Um tokenizer é responsável por pré-processar o texto em um formato que seja compreensível para o modelo. Primeiro, o tokenizer dividirá o texto em palavras chamadas *tokens*. Existem várias regras que regem o processo de tokenização, incluindo como dividir uma palavra e em que nível (saiba mais sobre tokenização [aqui](./tokenizer_summary)). A coisa mais importante a lembrar, porém, é que você precisa instanciar o tokenizer com o mesmo nome do modelo para garantir que está usando as mesmas regras de tokenização com as quais um modelo foi pré-treinado.
+
+Carregue um tokenizer com [`AutoTokenizer`]:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+Em seguida, o tokenizer converte os tokens em números para construir um tensor como entrada para o modelo. Isso é conhecido como o *vocabulário* do modelo.
+
+Passe o texto para o tokenizer:
+
+```py
+>>> encoding = tokenizer("We are very happy to show you the 🤗 Transformers library.")
+>>> print(encoding)
+{'input_ids': [101, 11312, 10320, 12495, 19308, 10114, 11391, 10855, 10103, 100, 58263, 13299, 119, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+O tokenizer retornará um dicionário contendo:
+
+* [input_ids](./glossary#input-ids): representações numéricas de seus tokens.
+* [atttention_mask](.glossary#attention-mask): indica quais tokens devem ser atendidos.
+
+Assim como o [`pipeline`], o tokenizer aceitará uma lista de entradas. Além disso, o tokenizer também pode preencher e truncar o texto para retornar um lote com comprimento uniforme:
+
+
+
+
+```py
+>>> pt_batch = tokenizer(
+... ["We are very happy to show you the 🤗 transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="pt",
+... )
+```
+
+
+
+```py
+>>> tf_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="tf",
+... )
+```
+
+
+
+Leia o tutorial de [pré-processamento](./pré-processamento) para obter mais detalhes sobre tokenização.
+
+### AutoModel
+
+
+
+🤗 Transformers fornecem uma maneira simples e unificada de carregar instâncias pré-treinadas. Isso significa que você pode carregar um [`AutoModel`] como carregaria um [`AutoTokenizer`]. A única diferença é selecionar o [`AutoModel`] correto para a tarefa. Como você está fazendo classificação de texto ou sequência, carregue [`AutoModelForSequenceClassification`]:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+Veja o [sumário de tarefas](./task_summary) para qual classe de [`AutoModel`] usar para cada tarefa.
+
+
+
+Agora você pode passar seu grupo de entradas pré-processadas diretamente para o modelo. Você apenas tem que descompactar o dicionário usando `**`:
+
+```py
+>>> pt_outputs = pt_model(**pt_batch)
+```
+
+O modelo gera as ativações finais no atributo `logits`. Aplique a função softmax aos `logits` para recuperar as probabilidades:
+
+```py
+>>> from torch import nn
+
+>>> pt_predictions = nn.functional.softmax(pt_outputs.logits, dim=-1)
+>>> print(pt_predictions)
+tensor([[0.0021, 0.0018, 0.0115, 0.2121, 0.7725],
+ [0.2084, 0.1826, 0.1969, 0.1755, 0.2365]], grad_fn=)
+```
+
+
+🤗 Transformers fornecem uma maneira simples e unificada de carregar instâncias pré-treinadas. Isso significa que você pode carregar um [`TFAutoModel`] como carregaria um [`AutoTokenizer`]. A única diferença é selecionar o [`TFAutoModel`] correto para a tarefa. Como você está fazendo classificação de texto ou sequência, carregue [`TFAutoModelForSequenceClassification`]:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+Veja o [sumário de tarefas](./task_summary) para qual classe de [`AutoModel`] usar para cada tarefa.
+
+
+
+Agora você pode passar seu grupo de entradas pré-processadas diretamente para o modelo através da passagem de chaves de dicionários ao tensor.
+
+```py
+>>> tf_outputs = tf_model(tf_batch)
+```
+
+O modelo gera as ativações finais no atributo `logits`. Aplique a função softmax aos `logits` para recuperar as probabilidades:
+
+```py
+>>> import tensorflow as tf
+
+>>> tf_predictions = tf.nn.softmax(tf_outputs.logits, axis=-1)
+>>> tf_predictions # doctest: +IGNORE_RESULT
+```
+
+
+
+
+
+Todos os modelos de 🤗 Transformers (PyTorch ou TensorFlow) geram tensores *antes* da função de ativação final (como softmax) pois essa função algumas vezes é fundida com a perda.
+
+
+
+
+Os modelos são um standard [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) ou um [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) para que você possa usá-los em seu loop de treinamento habitual. No entanto, para facilitar as coisas, 🤗 Transformers fornece uma classe [`Trainer`] para PyTorch que adiciona funcionalidade para treinamento distribuído, precisão mista e muito mais. Para o TensorFlow, você pode usar o método `fit` de [Keras](https://keras.io/). Consulte o [tutorial de treinamento](./training) para obter mais detalhes.
+
+
+
+As saídas do modelo 🤗 Transformers são classes de dados especiais para que seus atributos sejam preenchidos automaticamente em um IDE.
+As saídas do modelo também se comportam como uma tupla ou um dicionário (por exemplo, você pode indexar com um inteiro, uma parte ou uma string), caso em que os atributos `None` são ignorados.
+
+
+
+### Salvar um modelo
+
+
+
+Uma vez que seu modelo estiver afinado, você pode salvá-lo com seu Tokenizer usando [`PreTrainedModel.save_pretrained`]:
+
+```py
+>>> pt_save_directory = "./pt_save_pretrained"
+>>> tokenizer.save_pretrained(pt_save_directory) # doctest: +IGNORE_RESULT
+>>> pt_model.save_pretrained(pt_save_directory)
+```
+
+Quando você estiver pronto para usá-lo novamente, recarregue com [`PreTrainedModel.from_pretrained`]:
+
+```py
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("./pt_save_pretrained")
+```
+
+
+Uma vez que seu modelo estiver afinado, você pode salvá-lo com seu Tokenizer usando [`TFPreTrainedModel.save_pretrained`]:
+
+```py
+>>> tf_save_directory = "./tf_save_pretrained"
+>>> tokenizer.save_pretrained(tf_save_directory) # doctest: +IGNORE_RESULT
+>>> tf_model.save_pretrained(tf_save_directory)
+```
+
+Quando você estiver pronto para usá-lo novamente, recarregue com [`TFPreTrainedModel.from_pretrained`]
+
+```py
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("./tf_save_pretrained")
+```
+
+
+
+Um recurso particularmente interessante dos 🤗 Transformers é a capacidade de salvar um modelo e recarregá-lo como um modelo PyTorch ou TensorFlow. Use `from_pt` ou `from_tf` para converter o modelo de um framework para outro:
+
+
+
+
+```py
+>>> from transformers import AutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(pt_save_directory)
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(pt_save_directory, from_pt=True)
+```
+
+
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(tf_save_directory)
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(tf_save_directory, from_tf=True)
+```
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/run_scripts.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/run_scripts.md
new file mode 100644
index 0000000000000000000000000000000000000000..d4cc3973608d2c692244fd809174a216446dc294
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/run_scripts.md
@@ -0,0 +1,354 @@
+
+
+# Treinamento a partir de um script
+
+Junto com os 🤗 Transformers [notebooks](./notebooks), também há scripts de exemplo demonstrando como treinar um modelo para uma tarefa com [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch), [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow) ou [JAX/Flax](https://github.com/huggingface/transformers/tree/main/examples/flax).
+
+Você também encontrará scripts que usamos em nossos [projetos de pesquisa](https://github.com/huggingface/transformers/tree/main/examples/research_projects) e [exemplos legados](https://github.com/huggingface/transformers/tree/main/examples/legacy) que são principalmente contribuições da comunidade. Esses scripts não são mantidos ativamente e exigem uma versão específica de 🤗 Transformers que provavelmente será incompatível com a versão mais recente da biblioteca.
+
+Não se espera que os scripts de exemplo funcionem imediatamente em todos os problemas, você pode precisar adaptar o script ao problema que está tentando resolver. Para ajudá-lo com isso, a maioria dos scripts expõe totalmente como os dados são pré-processados, permitindo que você os edite conforme necessário para seu caso de uso.
+
+Para qualquer recurso que você gostaria de implementar em um script de exemplo, discuta-o no [fórum](https://discuss.huggingface.co/) ou em uma [issue](https://github.com/huggingface/transformers/issues) antes de enviar um Pull Request. Embora recebamos correções de bugs, é improvável que mesclaremos um Pull Request que adicione mais funcionalidades ao custo de legibilidade.
+
+Este guia mostrará como executar um exemplo de script de treinamento de sumarização em [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization) e [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/summarization). Espera-se que todos os exemplos funcionem com ambas as estruturas, a menos que especificado de outra forma.
+
+## Configuração
+
+Para executar com êxito a versão mais recente dos scripts de exemplo, você precisa **instalar o 🤗 Transformers da fonte** em um novo ambiente virtual:
+
+```bash
+git clone https://github.com/huggingface/transformers
+cd transformers
+pip install .
+```
+
+Para versões mais antigas dos scripts de exemplo, clique no botão abaixo:
+
+
+ Exemplos para versões antigas dos 🤗 Transformers
+
+
+
+Em seguida, mude seu clone atual dos 🤗 Transformers para uma versão específica, como v3.5.1, por exemplo:
+
+```bash
+git checkout tags/v3.5.1
+```
+
+Depois de configurar a versão correta da biblioteca, navegue até a pasta de exemplo de sua escolha e instale os requisitos específicos do exemplo:
+
+```bash
+pip install -r requirements.txt
+```
+
+## Executando um script
+
+
+
+
+O script de exemplo baixa e pré-processa um conjunto de dados da biblioteca 🤗 [Datasets](https://huggingface.co/docs/datasets/). Em seguida, o script ajusta um conjunto de dados com o [Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) em uma arquitetura que oferece suporte à sumarização. O exemplo a seguir mostra como ajustar [T5-small](https://huggingface.co/google-t5/t5-small) no conjunto de dados [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail). O modelo T5 requer um argumento `source_prefix` adicional devido à forma como foi treinado. Este prompt informa ao T5 que esta é uma tarefa de sumarização.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+Este outro script de exemplo baixa e pré-processa um conjunto de dados da biblioteca 🤗 [Datasets](https://huggingface.co/docs/datasets/). Em seguida, o script ajusta um conjunto de dados usando Keras em uma arquitetura que oferece suporte à sumarização. O exemplo a seguir mostra como ajustar [T5-small](https://huggingface.co/google-t5/t5-small) no conjunto de dados [CNN/DailyMail](https://huggingface.co/datasets/cnn_dailymail). O modelo T5 requer um argumento `source_prefix` adicional devido à forma como foi treinado. Este prompt informa ao T5 que esta é uma tarefa de sumarização.
+
+```bash
+python examples/tensorflow/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## Treinamento distribuído e precisão mista
+
+O [Trainer](https://huggingface.co/docs/transformers/main_classes/trainer) oferece suporte a treinamento distribuído e precisão mista, o que significa que você também pode usá-lo em um script. Para habilitar esses dois recursos:
+
+- Adicione o argumento `fp16` para habilitar a precisão mista.
+- Defina o número de GPUs a serem usadas com o argumento `nproc_per_node`.
+
+```bash
+torchrun \
+ --nproc_per_node 8 pytorch/summarization/run_summarization.py \
+ --fp16 \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+Os scripts do TensorFlow utilizam um [`MirroredStrategy`](https://www.tensorflow.org/guide/distributed_training#mirroredstrategy) para treinamento distribuído, e você não precisa adicionar argumentos adicionais ao script de treinamento. O script do TensorFlow usará várias GPUs por padrão, se estiverem disponíveis.
+
+## Executando um script em uma TPU
+
+
+
+As Unidades de Processamento de Tensor (TPUs) são projetadas especificamente para acelerar o desempenho. O PyTorch oferece suporte a TPUs com o compilador de aprendizado profundo [XLA](https://www.tensorflow.org/xla) (consulte [aqui](https://github.com/pytorch/xla/blob/master/README.md) para mais detalhes). Para usar uma TPU, inicie o script `xla_spawn.py` e use o argumento `num_cores` para definir o número de núcleos de TPU que você deseja usar.
+
+```bash
+python xla_spawn.py --num_cores 8 \
+ summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+
+
+As Unidades de Processamento de Tensor (TPUs) são projetadas especificamente para acelerar o desempenho. Os scripts do TensorFlow utilizam uma [`TPUStrategy`](https://www.tensorflow.org/guide/distributed_training#tpustrategy) para treinamento em TPUs. Para usar uma TPU, passe o nome do recurso TPU para o argumento `tpu`.
+
+```bash
+python run_summarization.py \
+ --tpu name_of_tpu_resource \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval
+```
+
+
+
+## Execute um script com 🤗 Accelerate
+
+🤗 [Accelerate](https://huggingface.co/docs/accelerate) é uma biblioteca somente do PyTorch que oferece um método unificado para treinar um modelo em vários tipos de configurações (CPU, multiplas GPUs, TPUs), mantendo visibilidade no loop de treinamento do PyTorch. Certifique-se de ter o 🤗 Accelerate instalado se ainda não o tiver:
+
+> Nota: Como o Accelerate está se desenvolvendo rapidamente, a versão git do Accelerate deve ser instalada para executar os scripts
+
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+Em vez do script `run_summarization.py`, você precisa usar o script `run_summarization_no_trainer.py`. Os scripts suportados pelo 🤗 Accelerate terão um arquivo `task_no_trainer.py` na pasta. Comece executando o seguinte comando para criar e salvar um arquivo de configuração:
+
+```bash
+accelerate config
+```
+
+Teste sua configuração para garantir que ela esteja corretamente configurada :
+
+```bash
+accelerate test
+```
+
+Agora você está pronto para iniciar o treinamento:
+
+```bash
+accelerate launch run_summarization_no_trainer.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir ~/tmp/tst-summarization
+```
+
+## Usando um conjunto de dados personalizado
+
+O script de resumo oferece suporte a conjuntos de dados personalizados, desde que sejam um arquivo CSV ou JSON. Ao usar seu próprio conjunto de dados, você precisa especificar vários argumentos adicionais:
+
+- `train_file` e `validation_file` especificam o caminho para seus arquivos de treinamento e validação respectivamente.
+- `text_column` é o texto de entrada para sumarização.
+- `summary_column` é o texto de destino para saída.
+
+Um script para sumarização usando um conjunto de dados customizado ficaria assim:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --train_file path_to_csv_or_jsonlines_file \
+ --validation_file path_to_csv_or_jsonlines_file \
+ --text_column text_column_name \
+ --summary_column summary_column_name \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --overwrite_output_dir \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --predict_with_generate
+```
+
+## Testando um script
+
+Geralmente, é uma boa ideia executar seu script em um número menor de exemplos de conjuntos de dados para garantir que tudo funcione conforme o esperado antes de se comprometer com um conjunto de dados inteiro, que pode levar horas para ser concluído. Use os seguintes argumentos para truncar o conjunto de dados para um número máximo de amostras:
+
+- `max_train_samples`
+- `max_eval_samples`
+- `max_predict_samples`
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --max_train_samples 50 \
+ --max_eval_samples 50 \
+ --max_predict_samples 50 \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
+
+Nem todos os scripts de exemplo suportam o argumento `max_predict_samples`. Se você não tiver certeza se seu script suporta este argumento, adicione o argumento `-h` para verificar:
+
+```bash
+examples/pytorch/summarization/run_summarization.py -h
+```
+
+## Retomar o treinamento a partir de um checkpoint
+
+Outra opção útil para habilitar é retomar o treinamento de um checkpoint anterior. Isso garantirá que você possa continuar de onde parou sem recomeçar se o seu treinamento for interrompido. Existem dois métodos para retomar o treinamento a partir de um checkpoint.
+
+O primeiro método usa o argumento `output_dir previous_output_dir` para retomar o treinamento do último checkpoint armazenado em `output_dir`. Neste caso, você deve remover `overwrite_output_dir`:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --output_dir previous_output_dir \
+ --predict_with_generate
+```
+
+O segundo método usa o argumento `resume_from_checkpoint path_to_specific_checkpoint` para retomar o treinamento de uma pasta de checkpoint específica.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --resume_from_checkpoint path_to_specific_checkpoint \
+ --predict_with_generate
+```
+
+## Compartilhando seu modelo
+
+Todos os scripts podem enviar seu modelo final para o [Model Hub](https://huggingface.co/models). Certifique-se de estar conectado ao Hugging Face antes de começar:
+
+```bash
+huggingface-cli login
+```
+
+Em seguida, adicione o argumento `push_to_hub` ao script. Este argumento criará um repositório com seu nome de usuário do Hugging Face e o nome da pasta especificado em `output_dir`.
+
+Para dar um nome específico ao seu repositório, use o argumento `push_to_hub_model_id` para adicioná-lo. O repositório será listado automaticamente em seu namespace.
+
+O exemplo a seguir mostra como fazer upload de um modelo com um nome de repositório específico:
+
+```bash
+python examples/pytorch/summarization/run_summarization.py
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --push_to_hub \
+ --push_to_hub_model_id finetuned-t5-cnn_dailymail \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --overwrite_output_dir \
+ --predict_with_generate
+```
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/serialization.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/serialization.md
new file mode 100644
index 0000000000000000000000000000000000000000..9e390f07bde41ded4d80a6d8faf75d563c3a2457
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/serialization.md
@@ -0,0 +1,502 @@
+
+
+# Exportando modelos para ONNX
+
+Se você precisar implantar modelos 🤗 Transformers em ambientes de produção, recomendamos
+exporta-los para um formato serializado que pode ser carregado e executado em
+tempos de execução e hardware. Neste guia, mostraremos como exportar modelos 🤗 Transformers
+para [ONNX (Open Neural Network eXchange)](http://onnx.ai).
+
+
+
+Uma vez exportado, um modelo pode ser otimizado para inferência por meio de técnicas como
+quantização e poda. Se você estiver interessado em otimizar seus modelos para serem executados com
+máxima eficiência, confira a biblioteca [🤗 Optimum
+](https://github.com/huggingface/optimum).
+
+
+
+ONNX é um padrão aberto que define um conjunto comum de operadores e um formato de arquivo comum
+para representar modelos de aprendizado profundo em uma ampla variedade de estruturas, incluindo PyTorch e
+TensorFlow. Quando um modelo é exportado para o formato ONNX, esses operadores são usados para
+construir um grafo computacional (muitas vezes chamado de _representação intermediária_) que
+representa o fluxo de dados através da rede neural.
+
+Ao expor um grafo com operadores e tipos de dados padronizados, o ONNX facilita a
+alternar entre os frameworks. Por exemplo, um modelo treinado em PyTorch pode ser exportado para
+formato ONNX e depois importado no TensorFlow (e vice-versa).
+
+🤗 Transformers fornece um pacote [`transformers.onnx`](main_classes/onnx) que permite
+que você converta os checkpoints do modelo em um grafo ONNX aproveitando os objetos de configuração.
+Esses objetos de configuração vêm prontos para várias arquiteturas de modelo e são
+projetado para ser facilmente extensível a outras arquiteturas.
+
+As configurações prontas incluem as seguintes arquiteturas:
+
+
+
+- ALBERT
+- BART
+- BEiT
+- BERT
+- BigBird
+- BigBird-Pegasus
+- Blenderbot
+- BlenderbotSmall
+- BLOOM
+- CamemBERT
+- CLIP
+- CodeGen
+- Conditional DETR
+- ConvBERT
+- ConvNeXT
+- ConvNeXTV2
+- Data2VecText
+- Data2VecVision
+- DeBERTa
+- DeBERTa-v2
+- DeiT
+- DETR
+- DistilBERT
+- ELECTRA
+- ERNIE
+- FlauBERT
+- GPT Neo
+- GPT-J
+- GroupViT
+- I-BERT
+- LayoutLM
+- LayoutLMv3
+- LeViT
+- Longformer
+- LongT5
+- M2M100
+- Marian
+- mBART
+- MobileBERT
+- MobileViT
+- MT5
+- OpenAI GPT-2
+- OWL-ViT
+- Perceiver
+- PLBart
+- ResNet
+- RoBERTa
+- RoFormer
+- SegFormer
+- SqueezeBERT
+- Swin Transformer
+- T5
+- Table Transformer
+- Vision Encoder decoder
+- ViT
+- XLM
+- XLM-RoBERTa
+- XLM-RoBERTa-XL
+- YOLOS
+
+Nas próximas duas seções, mostraremos como:
+
+* Exportar um modelo suportado usando o pacote `transformers.onnx`.
+* Exportar um modelo personalizado para uma arquitetura sem suporte.
+
+## Exportando um modelo para ONNX
+
+Para exportar um modelo 🤗 Transformers para o ONNX, primeiro você precisa instalar algumas
+dependências extras:
+
+```bash
+pip install transformers[onnx]
+```
+
+O pacote `transformers.onnx` pode então ser usado como um módulo Python:
+
+```bash
+python -m transformers.onnx --help
+
+usage: Hugging Face Transformers ONNX exporter [-h] -m MODEL [--feature {causal-lm, ...}] [--opset OPSET] [--atol ATOL] output
+
+positional arguments:
+ output Path indicating where to store generated ONNX model.
+
+optional arguments:
+ -h, --help show this help message and exit
+ -m MODEL, --model MODEL
+ Model ID on huggingface.co or path on disk to load model from.
+ --feature {causal-lm, ...}
+ The type of features to export the model with.
+ --opset OPSET ONNX opset version to export the model with.
+ --atol ATOL Absolute difference tolerance when validating the model.
+```
+
+A exportação de um checkpoint usando uma configuração pronta pode ser feita da seguinte forma:
+
+```bash
+python -m transformers.onnx --model=distilbert/distilbert-base-uncased onnx/
+```
+
+Você deve ver os seguintes logs:
+
+```bash
+Validating ONNX model...
+ -[✓] ONNX model output names match reference model ({'last_hidden_state'})
+ - Validating ONNX Model output "last_hidden_state":
+ -[✓] (2, 8, 768) matches (2, 8, 768)
+ -[✓] all values close (atol: 1e-05)
+All good, model saved at: onnx/model.onnx
+```
+
+Isso exporta um grafo ONNX do ponto de verificação definido pelo argumento `--model`. Nisso
+Por exemplo, é `distilbert/distilbert-base-uncased`, mas pode ser qualquer checkpoint no Hugging
+Face Hub ou um armazenado localmente.
+
+O arquivo `model.onnx` resultante pode ser executado em um dos [muitos
+aceleradores](https://onnx.ai/supported-tools.html#deployModel) que suportam o ONNX
+padrão. Por exemplo, podemos carregar e executar o modelo com [ONNX
+Tempo de execução](https://onnxruntime.ai/) da seguinte forma:
+
+```python
+>>> from transformers import AutoTokenizer
+>>> from onnxruntime import InferenceSession
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> session = InferenceSession("onnx/model.onnx")
+>>> # ONNX Runtime expects NumPy arrays as input
+>>> inputs = tokenizer("Using DistilBERT with ONNX Runtime!", return_tensors="np")
+>>> outputs = session.run(output_names=["last_hidden_state"], input_feed=dict(inputs))
+```
+
+Os nomes de saída necessários (como `["last_hidden_state"]`) podem ser obtidos pegando uma
+ configuração ONNX de cada modelo. Por exemplo, para DistilBERT temos:
+
+```python
+>>> from transformers.models.distilbert import DistilBertConfig, DistilBertOnnxConfig
+
+>>> config = DistilBertConfig()
+>>> onnx_config = DistilBertOnnxConfig(config)
+>>> print(list(onnx_config.outputs.keys()))
+["last_hidden_state"]
+```
+
+O processo é idêntico para os checkpoints do TensorFlow no Hub. Por exemplo, podemos
+exportar um checkpoint TensorFlow puro do [Keras
+](https://huggingface.co/keras-io) da seguinte forma:
+
+```bash
+python -m transformers.onnx --model=keras-io/transformers-qa onnx/
+```
+
+Para exportar um modelo armazenado localmente, você precisará ter os pesos e
+arquivos tokenizer armazenados em um diretório. Por exemplo, podemos carregar e salvar um checkpoint como:
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> # Load tokenizer and PyTorch weights form the Hub
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+>>> # Save to disk
+>>> tokenizer.save_pretrained("local-pt-checkpoint")
+>>> pt_model.save_pretrained("local-pt-checkpoint")
+```
+
+Uma vez que o checkpoint é salvo, podemos exportá-lo para o ONNX apontando o `--model`
+argumento do pacote `transformers.onnx` para o diretório desejado:
+
+```bash
+python -m transformers.onnx --model=local-pt-checkpoint onnx/
+```
+
+```python
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> # Load tokenizer and TensorFlow weights from the Hub
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+>>> # Save to disk
+>>> tokenizer.save_pretrained("local-tf-checkpoint")
+>>> tf_model.save_pretrained("local-tf-checkpoint")
+```
+
+Uma vez que o checkpoint é salvo, podemos exportá-lo para o ONNX apontando o `--model`
+argumento do pacote `transformers.onnx` para o diretório desejado:
+
+```bash
+python -m transformers.onnx --model=local-tf-checkpoint onnx/
+```
+
+## Selecionando features para diferentes tarefas do modelo
+
+Cada configuração pronta vem com um conjunto de _features_ que permitem exportar
+modelos para diferentes tipos de tarefas. Conforme mostrado na tabela abaixo, cada recurso é
+associado a uma `AutoClass` diferente:
+
+| Feature | Auto Class |
+| ------------------------------------ | ------------------------------------ |
+| `causal-lm`, `causal-lm-with-past` | `AutoModelForCausalLM` |
+| `default`, `default-with-past` | `AutoModel` |
+| `masked-lm` | `AutoModelForMaskedLM` |
+| `question-answering` | `AutoModelForQuestionAnswering` |
+| `seq2seq-lm`, `seq2seq-lm-with-past` | `AutoModelForSeq2SeqLM` |
+| `sequence-classification` | `AutoModelForSequenceClassification` |
+| `token-classification` | `AutoModelForTokenClassification` |
+
+Para cada configuração, você pode encontrar a lista de recursos suportados por meio do
+[`~transformers.onnx.FeaturesManager`]. Por exemplo, para DistilBERT temos:
+
+```python
+>>> from transformers.onnx.features import FeaturesManager
+
+>>> distilbert_features = list(FeaturesManager.get_supported_features_for_model_type("distilbert").keys())
+>>> print(distilbert_features)
+["default", "masked-lm", "causal-lm", "sequence-classification", "token-classification", "question-answering"]
+```
+
+Você pode então passar um desses recursos para o argumento `--feature` no
+pacote `transformers.onnx`. Por exemplo, para exportar um modelo de classificação de texto, podemos
+escolher um modelo ajustado no Hub e executar:
+
+```bash
+python -m transformers.onnx --model=distilbert/distilbert-base-uncased-finetuned-sst-2-english \
+ --feature=sequence-classification onnx/
+```
+
+Isso exibe os seguintes logs:
+
+```bash
+Validating ONNX model...
+ -[✓] ONNX model output names match reference model ({'logits'})
+ - Validating ONNX Model output "logits":
+ -[✓] (2, 2) matches (2, 2)
+ -[✓] all values close (atol: 1e-05)
+All good, model saved at: onnx/model.onnx
+```
+
+Observe que, neste caso, os nomes de saída do modelo ajustado são `logits`
+em vez do `last_hidden_state` que vimos com o checkpoint `distilbert/distilbert-base-uncased`
+mais cedo. Isso é esperado, pois o modelo ajustado (fine-tuned) possui uma cabeça de classificação de sequência.
+
+
+
+Os recursos que têm um sufixo `with-pass` (como `causal-lm-with-pass`) correspondem a
+classes de modelo com estados ocultos pré-computados (chave e valores nos blocos de atenção)
+que pode ser usado para decodificação autorregressiva rápida.
+
+
+
+
+
+Para modelos do tipo `VisionEncoderDecoder`, as partes do codificador e do decodificador são
+exportados separadamente como dois arquivos ONNX chamados `encoder_model.onnx` e `decoder_model.onnx` respectivamente.
+
+
+
+## Exportando um modelo para uma arquitetura sem suporte
+
+Se você deseja exportar um modelo cuja arquitetura não é suportada nativamente pela
+biblioteca, há três etapas principais a seguir:
+
+1. Implemente uma configuração ONNX personalizada.
+2. Exporte o modelo para o ONNX.
+3. Valide as saídas do PyTorch e dos modelos exportados.
+
+Nesta seção, veremos como o DistilBERT foi implementado para mostrar o que está envolvido
+em cada passo.
+
+### Implementando uma configuração ONNX personalizada
+
+Vamos começar com o objeto de configuração ONNX. Fornecemos três classes abstratas que
+você deve herdar, dependendo do tipo de arquitetura de modelo que deseja exportar:
+
+* Modelos baseados em codificador herdam de [`~onnx.config.OnnxConfig`]
+* Modelos baseados em decodificador herdam de [`~onnx.config.OnnxConfigWithPast`]
+* Os modelos codificador-decodificador herdam de [`~onnx.config.OnnxSeq2SeqConfigWithPast`]
+
+
+
+Uma boa maneira de implementar uma configuração ONNX personalizada é observar as
+implementação no arquivo `configuration_.py` de uma arquitetura semelhante.
+
+
+
+Como o DistilBERT é um modelo baseado em codificador, sua configuração é herdada de
+`OnnxConfig`:
+
+```python
+>>> from typing import Mapping, OrderedDict
+>>> from transformers.onnx import OnnxConfig
+
+
+>>> class DistilBertOnnxConfig(OnnxConfig):
+... @property
+... def inputs(self) -> Mapping[str, Mapping[int, str]]:
+... return OrderedDict(
+... [
+... ("input_ids", {0: "batch", 1: "sequence"}),
+... ("attention_mask", {0: "batch", 1: "sequence"}),
+... ]
+... )
+```
+
+Todo objeto de configuração deve implementar a propriedade `inputs` e retornar um mapeamento,
+onde cada chave corresponde a uma entrada esperada e cada valor indica o eixo
+dessa entrada. Para o DistilBERT, podemos ver que duas entradas são necessárias: `input_ids` e
+`attention_mask`. Essas entradas têm a mesma forma de `(batch_size, sequence_length)`
+é por isso que vemos os mesmos eixos usados na configuração.
+
+
+
+Notice that `inputs` property for `DistilBertOnnxConfig` returns an `OrderedDict`. This
+ensures that the inputs are matched with their relative position within the
+`PreTrainedModel.forward()` method when tracing the graph. We recommend using an
+`OrderedDict` for the `inputs` and `outputs` properties when implementing custom ONNX
+configurations.
+
+Observe que a propriedade `inputs` para `DistilBertOnnxConfig` retorna um `OrderedDict`. Este
+garante que as entradas sejam combinadas com sua posição relativa dentro do
+método `PreTrainedModel.forward()` ao traçar o grafo. Recomendamos o uso de um
+`OrderedDict` para as propriedades `inputs` e `outputs` ao implementar configurações personalizadas ONNX.
+
+
+
+Depois de implementar uma configuração ONNX, você pode instanciá-la fornecendo a
+configuração do modelo base da seguinte forma:
+
+```python
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased")
+>>> onnx_config = DistilBertOnnxConfig(config)
+```
+
+O objeto resultante tem várias propriedades úteis. Por exemplo, você pode visualizar o conjunto de operadores ONNX
+ que será usado durante a exportação:
+
+```python
+>>> print(onnx_config.default_onnx_opset)
+11
+```
+
+Você também pode visualizar as saídas associadas ao modelo da seguinte forma:
+
+```python
+>>> print(onnx_config.outputs)
+OrderedDict([("last_hidden_state", {0: "batch", 1: "sequence"})])
+```
+
+Observe que a propriedade outputs segue a mesma estrutura das entradas; ele retorna um
+`OrderedDict` de saídas nomeadas e suas formas. A estrutura de saída está ligada a
+escolha do recurso com o qual a configuração é inicializada. Por padrão, a configuração do ONNX
+é inicializada com o recurso `default` que corresponde à exportação de um
+modelo carregado com a classe `AutoModel`. Se você deseja exportar um modelo para outra tarefa,
+apenas forneça um recurso diferente para o argumento `task` quando você inicializar a configuração ONNX
+. Por exemplo, se quisermos exportar o DistilBERT com uma sequência
+de classificação, poderíamos usar:
+
+```python
+>>> from transformers import AutoConfig
+
+>>> config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased")
+>>> onnx_config_for_seq_clf = DistilBertOnnxConfig(config, task="sequence-classification")
+>>> print(onnx_config_for_seq_clf.outputs)
+OrderedDict([('logits', {0: 'batch'})])
+```
+
+
+
+Todas as propriedades e métodos básicos associados a [`~onnx.config.OnnxConfig`] e
+as outras classes de configuração podem ser substituídas se necessário. Confira [`BartOnnxConfig`]
+para um exemplo avançado.
+
+
+
+### Exportando um modelo
+
+Depois de ter implementado a configuração do ONNX, o próximo passo é exportar o modelo.
+Aqui podemos usar a função `export()` fornecida pelo pacote `transformers.onnx`.
+Esta função espera a configuração do ONNX, juntamente com o modelo base e o tokenizer,
+e o caminho para salvar o arquivo exportado:
+
+```python
+>>> from pathlib import Path
+>>> from transformers.onnx import export
+>>> from transformers import AutoTokenizer, AutoModel
+
+>>> onnx_path = Path("model.onnx")
+>>> model_ckpt = "distilbert/distilbert-base-uncased"
+>>> base_model = AutoModel.from_pretrained(model_ckpt)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_ckpt)
+
+>>> onnx_inputs, onnx_outputs = export(tokenizer, base_model, onnx_config, onnx_config.default_onnx_opset, onnx_path)
+```
+
+Os `onnx_inputs` e `onnx_outputs` retornados pela função `export()` são listas de
+ chaves definidas nas propriedades `inputs` e `outputs` da configuração. Uma vez que o
+modelo é exportado, você pode testar se o modelo está bem formado da seguinte forma:
+
+```python
+>>> import onnx
+
+>>> onnx_model = onnx.load("model.onnx")
+>>> onnx.checker.check_model(onnx_model)
+```
+
+
+
+Se o seu modelo for maior que 2GB, você verá que muitos arquivos adicionais são criados
+durante a exportação. Isso é _esperado_ porque o ONNX usa [Protocol
+Buffers](https://developers.google.com/protocol-buffers/) para armazenar o modelo e estes
+têm um limite de tamanho de 2GB. Veja a [ONNX
+documentação](https://github.com/onnx/onnx/blob/master/docs/ExternalData.md) para
+instruções sobre como carregar modelos com dados externos.
+
+
+
+### Validando a saída dos modelos
+
+A etapa final é validar se as saídas do modelo base e exportado concordam
+dentro de alguma tolerância absoluta. Aqui podemos usar a função `validate_model_outputs()`
+fornecida pelo pacote `transformers.onnx` da seguinte forma:
+
+```python
+>>> from transformers.onnx import validate_model_outputs
+
+>>> validate_model_outputs(
+... onnx_config, tokenizer, base_model, onnx_path, onnx_outputs, onnx_config.atol_for_validation
+... )
+```
+
+Esta função usa o método [`~transformers.onnx.OnnxConfig.generate_dummy_inputs`] para
+gerar entradas para o modelo base e o exportado, e a tolerância absoluta pode ser
+definida na configuração. Geralmente encontramos concordância numérica em 1e-6 a 1e-4
+de alcance, embora qualquer coisa menor que 1e-3 provavelmente esteja OK.
+
+## Contribuindo com uma nova configuração para 🤗 Transformers
+
+Estamos procurando expandir o conjunto de configurações prontas e receber contribuições
+da comunidade! Se você gostaria de contribuir para a biblioteca, você
+precisará:
+
+* Implemente a configuração do ONNX no arquivo `configuration_.py` correspondente
+Arquivo
+* Incluir a arquitetura do modelo e recursos correspondentes em
+ [`~onnx.features.FeatureManager`]
+* Adicione sua arquitetura de modelo aos testes em `test_onnx_v2.py`
+
+Confira como ficou a configuração do [IBERT
+](https://github.com/huggingface/transformers/pull/14868/files) para obter uma
+idéia do que está envolvido.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/tasks/sequence_classification.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/tasks/sequence_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..a2e6865c92e5b619d2427c972bf54122dfcc9096
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/tasks/sequence_classification.md
@@ -0,0 +1,216 @@
+
+
+# Classificação de texto
+
+
+
+A classificação de texto é uma tarefa comum de NLP que atribui um rótulo ou classe a um texto. Existem muitas aplicações práticas de classificação de texto amplamente utilizadas em produção por algumas das maiores empresas da atualidade. Uma das formas mais populares de classificação de texto é a análise de sentimento, que atribui um rótulo como positivo, negativo ou neutro a um texto.
+
+Este guia mostrará como realizar o fine-tuning do [DistilBERT](https://huggingface.co/distilbert/distilbert-base-uncased) no conjunto de dados [IMDb](https://huggingface.co/datasets/imdb) para determinar se a crítica de filme é positiva ou negativa.
+
+
+
+Consulte a [página de tarefas de classificação de texto](https://huggingface.co/tasks/text-classification) para obter mais informações sobre outras formas de classificação de texto e seus modelos, conjuntos de dados e métricas associados.
+
+
+
+## Carregue o conjunto de dados IMDb
+
+Carregue o conjunto de dados IMDb utilizando a biblioteca 🤗 Datasets:
+
+```py
+>>> from datasets import load_dataset
+
+>>> imdb = load_dataset("imdb")
+```
+
+Em seguida, dê uma olhada em um exemplo:
+
+```py
+>>> imdb["test"][0]
+{
+ "label": 0,
+ "text": "I love sci-fi and am willing to put up with a lot. Sci-fi movies/TV are usually underfunded, under-appreciated and misunderstood. I tried to like this, I really did, but it is to good TV sci-fi as Babylon 5 is to Star Trek (the original). Silly prosthetics, cheap cardboard sets, stilted dialogues, CG that doesn't match the background, and painfully one-dimensional characters cannot be overcome with a 'sci-fi' setting. (I'm sure there are those of you out there who think Babylon 5 is good sci-fi TV. It's not. It's clichéd and uninspiring.) While US viewers might like emotion and character development, sci-fi is a genre that does not take itself seriously (cf. Star Trek). It may treat important issues, yet not as a serious philosophy. It's really difficult to care about the characters here as they are not simply foolish, just missing a spark of life. Their actions and reactions are wooden and predictable, often painful to watch. The makers of Earth KNOW it's rubbish as they have to always say \"Gene Roddenberry's Earth...\" otherwise people would not continue watching. Roddenberry's ashes must be turning in their orbit as this dull, cheap, poorly edited (watching it without advert breaks really brings this home) trudging Trabant of a show lumbers into space. Spoiler. So, kill off a main character. And then bring him back as another actor. Jeeez! Dallas all over again.",
+}
+```
+
+Existem dois campos neste dataset:
+
+- `text`: uma string contendo o texto da crítica do filme.
+- `label`: um valor que pode ser `0` para uma crítica negativa ou `1` para uma crítica positiva.
+
+## Pré-processamento dos dados
+
+Carregue o tokenizador do DistilBERT para processar o campo `text`:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Crie uma função de pré-processamento para tokenizar o campo `text` e truncar as sequências para que não sejam maiores que o comprimento máximo de entrada do DistilBERT:
+
+```py
+>>> def preprocess_function(examples):
+... return tokenizer(examples["text"], truncation=True)
+```
+
+Use a função [`map`](https://huggingface.co/docs/datasets/process#map) do 🤗 Datasets para aplicar a função de pré-processamento em todo o conjunto de dados. Você pode acelerar a função `map` definindo `batched=True` para processar vários elementos do conjunto de dados de uma só vez:
+
+```py
+tokenized_imdb = imdb.map(preprocess_function, batched=True)
+```
+
+Use o [`DataCollatorWithPadding`] para criar um batch de exemplos. Ele também *preencherá dinamicamente* seu texto até o comprimento do elemento mais longo em seu batch, para que os exemplos do batch tenham um comprimento uniforme. Embora seja possível preencher seu texto com a função `tokenizer` definindo `padding=True`, o preenchimento dinâmico utilizando um data collator é mais eficiente.
+
+
+
+```py
+>>> from transformers import DataCollatorWithPadding
+
+>>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+```
+
+
+```py
+>>> from transformers import DataCollatorWithPadding
+
+>>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer, return_tensors="tf")
+```
+
+
+
+## Train
+
+
+
+Carregue o DistilBERT com [`AutoModelForSequenceClassification`] junto com o número de rótulos esperados:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased", num_labels=2)
+```
+
+
+
+Se você não estiver familiarizado com o fine-tuning de um modelo com o [`Trainer`], dê uma olhada no tutorial básico [aqui](../training#finetune-with-trainer)!
+
+
+
+Nesse ponto, restam apenas três passos:
+
+1. Definir seus hiperparâmetros de treinamento em [`TrainingArguments`].
+2. Passar os argumentos de treinamento para o [`Trainer`] junto com o modelo, conjunto de dados, tokenizador e o data collator.
+3. Chamar a função [`~Trainer.train`] para executar o fine-tuning do seu modelo.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="./results",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=5,
+... weight_decay=0.01,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_imdb["train"],
+... eval_dataset=tokenized_imdb["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+
+
+O [`Trainer`] aplicará o preenchimento dinâmico por padrão quando você definir o argumento `tokenizer` dele. Nesse caso, você não precisa especificar um data collator explicitamente.
+
+
+
+
+Para executar o fine-tuning de um modelo no TensorFlow, comece convertendo seu conjunto de dados para o formato `tf.data.Dataset` com [`to_tf_dataset`](https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.to_tf_dataset). Nessa execução você deverá especificar as entradas e rótulos (no parâmetro `columns`), se deseja embaralhar o conjunto de dados, o tamanho do batch e o data collator:
+
+```py
+>>> tf_train_set = tokenized_imdb["train"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "label"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = tokenized_imdb["test"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "label"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+
+
+Se você não estiver familiarizado com o fine-tuning de um modelo com o Keras, dê uma olhada no tutorial básico [aqui](training#finetune-with-keras)!
+
+
+
+Configure o otimizador e alguns hiperparâmetros de treinamento:
+
+```py
+>>> from transformers import create_optimizer
+>>> import tensorflow as tf
+
+>>> batch_size = 16
+>>> num_epochs = 5
+>>> batches_per_epoch = len(tokenized_imdb["train"]) // batch_size
+>>> total_train_steps = int(batches_per_epoch * num_epochs)
+>>> optimizer, schedule = create_optimizer(init_lr=2e-5, num_warmup_steps=0, num_train_steps=total_train_steps)
+```
+
+Carregue o DistilBERT com [`TFAutoModelForSequenceClassification`] junto com o número de rótulos esperados:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased", num_labels=2)
+```
+
+Configure o modelo para treinamento com o método [`compile`](https://keras.io/api/models/model_training_apis/#compile-method):
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+Chame o método [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) para executar o fine-tuning do modelo:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3)
+```
+
+
+
+
+
+Para obter um exemplo mais aprofundado de como executar o fine-tuning de um modelo para classificação de texto, dê uma olhada nesse [notebook utilizando PyTorch](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb) ou nesse [notebook utilizando TensorFlow](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification-tf.ipynb).
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/tasks/token_classification.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/tasks/token_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..45ce0d87429c58cf2f27b7b50666cb42df100ec4
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/tasks/token_classification.md
@@ -0,0 +1,272 @@
+
+
+# Classificação de tokens
+
+
+
+A classificação de tokens atribui um rótulo a tokens individuais em uma frase. Uma das tarefas de classificação de tokens mais comuns é o Reconhecimento de Entidade Nomeada, também chamada de NER (sigla em inglês para Named Entity Recognition). O NER tenta encontrar um rótulo para cada entidade em uma frase, como uma pessoa, local ou organização.
+
+Este guia mostrará como realizar o fine-tuning do [DistilBERT](https://huggingface.co/distilbert/distilbert-base-uncased) no conjunto de dados [WNUT 17](https://huggingface.co/datasets/wnut_17) para detectar novas entidades.
+
+
+
+Consulte a [página de tarefas de classificação de tokens](https://huggingface.co/tasks/token-classification) para obter mais informações sobre outras formas de classificação de tokens e seus modelos, conjuntos de dados e métricas associadas.
+
+
+
+## Carregando o conjunto de dados WNUT 17
+
+Carregue o conjunto de dados WNUT 17 da biblioteca 🤗 Datasets:
+
+```py
+>>> from datasets import load_dataset
+
+>>> wnut = load_dataset("wnut_17")
+```
+
+E dê uma olhada em um exemplo:
+
+```py
+>>> wnut["train"][0]
+{'id': '0',
+ 'ner_tags': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 7, 8, 8, 0, 7, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'tokens': ['@paulwalk', 'It', "'s", 'the', 'view', 'from', 'where', 'I', "'m", 'living', 'for', 'two', 'weeks', '.', 'Empire', 'State', 'Building', '=', 'ESB', '.', 'Pretty', 'bad', 'storm', 'here', 'last', 'evening', '.']
+}
+```
+
+Cada número em `ner_tags` representa uma entidade. Converta o número em um rótulo para obter mais informações:
+
+```py
+>>> label_list = wnut["train"].features[f"ner_tags"].feature.names
+>>> label_list
+[
+ "O",
+ "B-corporation",
+ "I-corporation",
+ "B-creative-work",
+ "I-creative-work",
+ "B-group",
+ "I-group",
+ "B-location",
+ "I-location",
+ "B-person",
+ "I-person",
+ "B-product",
+ "I-product",
+]
+```
+
+O `ner_tag` descreve uma entidade, como uma organização, local ou pessoa. A letra que prefixa cada `ner_tag` indica a posição do token da entidade:
+
+- `B-` indica o início de uma entidade.
+- `I-` indica que um token está contido dentro da mesma entidade (por exemplo, o token `State` pode fazer parte de uma entidade como `Empire State Building`).
+- `0` indica que o token não corresponde a nenhuma entidade.
+
+## Pré-processamento
+
+
+
+Carregue o tokenizer do DistilBERT para processar os `tokens`:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Como a entrada já foi dividida em palavras, defina `is_split_into_words=True` para tokenizar as palavras em subpalavras:
+
+```py
+>>> tokenized_input = tokenizer(example["tokens"], is_split_into_words=True)
+>>> tokens = tokenizer.convert_ids_to_tokens(tokenized_input["input_ids"])
+>>> tokens
+['[CLS]', '@', 'paul', '##walk', 'it', "'", 's', 'the', 'view', 'from', 'where', 'i', "'", 'm', 'living', 'for', 'two', 'weeks', '.', 'empire', 'state', 'building', '=', 'es', '##b', '.', 'pretty', 'bad', 'storm', 'here', 'last', 'evening', '.', '[SEP]']
+```
+
+Ao adicionar os tokens especiais `[CLS]` e `[SEP]` e a tokenização de subpalavras uma incompatibilidade é gerada entre a entrada e os rótulos. Uma única palavra correspondente a um único rótulo pode ser dividida em duas subpalavras. Você precisará realinhar os tokens e os rótulos da seguinte forma:
+
+1. Mapeie todos os tokens para a palavra correspondente com o método [`word_ids`](https://huggingface.co/docs/tokenizers/python/latest/api/reference.html#tokenizers.Encoding.word_ids).
+2. Atribuindo o rótulo `-100` aos tokens especiais `[CLS]` e `[SEP]` para que a função de loss do PyTorch ignore eles.
+3. Rotular apenas o primeiro token de uma determinada palavra. Atribuindo `-100` a outros subtokens da mesma palavra.
+
+Aqui está como você pode criar uma função para realinhar os tokens e rótulos e truncar sequências para não serem maiores que o comprimento máximo de entrada do DistilBERT:
+
+```py
+>>> def tokenize_and_align_labels(examples):
+... tokenized_inputs = tokenizer(examples["tokens"], truncation=True, is_split_into_words=True)
+
+... labels = []
+... for i, label in enumerate(examples[f"ner_tags"]):
+... word_ids = tokenized_inputs.word_ids(batch_index=i) # Map tokens to their respective word.
+... previous_word_idx = None
+... label_ids = []
+... for word_idx in word_ids: # Set the special tokens to -100.
+... if word_idx is None:
+... label_ids.append(-100)
+... elif word_idx != previous_word_idx: # Only label the first token of a given word.
+... label_ids.append(label[word_idx])
+... else:
+... label_ids.append(-100)
+... previous_word_idx = word_idx
+... labels.append(label_ids)
+
+... tokenized_inputs["labels"] = labels
+... return tokenized_inputs
+```
+
+Use a função [`map`](https://huggingface.co/docs/datasets/process#map) do 🤗 Datasets para tokenizar e alinhar os rótulos em todo o conjunto de dados. Você pode acelerar a função `map` configurando `batched=True` para processar vários elementos do conjunto de dados de uma só vez:
+
+```py
+>>> tokenized_wnut = wnut.map(tokenize_and_align_labels, batched=True)
+```
+
+Use o [`DataCollatorForTokenClassification`] para criar um batch de exemplos. Ele também *preencherá dinamicamente* seu texto e rótulos para o comprimento do elemento mais longo em seu batch, para que tenham um comprimento uniforme. Embora seja possível preencher seu texto na função `tokenizer` configurando `padding=True`, o preenchimento dinâmico é mais eficiente.
+
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer)
+```
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer, return_tensors="tf")
+```
+
+
+
+## Treinamento
+
+
+
+Carregue o DistilBERT com o [`AutoModelForTokenClassification`] junto com o número de rótulos esperados:
+
+```py
+>>> from transformers import AutoModelForTokenClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased", num_labels=14)
+```
+
+
+
+Se você não estiver familiarizado com o fine-tuning de um modelo com o [`Trainer`], dê uma olhada no tutorial básico [aqui](../training#finetune-with-trainer)!
+
+
+
+Nesse ponto, restam apenas três passos:
+
+1. Definir seus hiperparâmetros de treinamento em [`TrainingArguments`].
+2. Passar os argumentos de treinamento para o [`Trainer`] junto com o modelo, conjunto de dados, tokenizador e o data collator.
+3. Chamar a função [`~Trainer.train`] para executar o fine-tuning do seu modelo.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="./results",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_wnut["train"],
+... eval_dataset=tokenized_wnut["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+
+Para executar o fine-tuning de um modelo no TensorFlow, comece convertendo seu conjunto de dados para o formato `tf.data.Dataset` com [`to_tf_dataset`](https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.to_tf_dataset). Nessa execução você deverá especificar as entradas e rótulos (no parâmetro `columns`), se deseja embaralhar o conjunto de dados, o tamanho do batch e o data collator:
+
+```py
+>>> tf_train_set = tokenized_wnut["train"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "labels"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = tokenized_wnut["validation"].to_tf_dataset(
+... columns=["attention_mask", "input_ids", "labels"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+
+
+Se você não estiver familiarizado com o fine-tuning de um modelo com o Keras, dê uma olhada no tutorial básico [aqui](training#finetune-with-keras)!
+
+
+
+Configure o otimizador e alguns hiperparâmetros de treinamento:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_train_epochs = 3
+>>> num_train_steps = (len(tokenized_wnut["train"]) // batch_size) * num_train_epochs
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=2e-5,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=0.01,
+... num_warmup_steps=0,
+... )
+```
+
+Carregue o DistilBERT com o [`TFAutoModelForTokenClassification`] junto com o número de rótulos esperados:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("distilbert/distilbert-base-uncased", num_labels=2)
+```
+
+Configure o modelo para treinamento com o método [`compile`](https://keras.io/api/models/model_training_apis/#compile-method):
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+Chame o método [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) para executar o fine-tuning do modelo:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3)
+```
+
+
+
+
+
+Para obter um exemplo mais aprofundado de como executar o fine-tuning de um modelo para classificação de tokens, dê uma olhada nesse [notebook utilizando PyTorch](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb) ou nesse [notebook utilizando TensorFlow](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification-tf.ipynb).
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/training.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/training.md
new file mode 100644
index 0000000000000000000000000000000000000000..67294baee35c1f8108ddfb65fdba2165c65e6ee2
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/training.md
@@ -0,0 +1,416 @@
+
+
+# Fine-tuning de um modelo pré-treinado
+
+[[open-in-colab]]
+
+O uso de um modelo pré-treinado tem importantes vantagens. Redução do custo computacional, a pegada de carbono, e te
+permite utilizar modelos de última geração sem ter que treinar um novo desde o início.
+O 🤗 Transformers proporciona acesso a milhares de modelos pré-treinados numa ampla gama de tarefas.
+Quando utilizar um modelo pré-treinado, treine-o com um dataset específico para a sua tarefa.
+Isto é chamado de fine-tuning, uma técnica de treinamento incrivelmente poderosa. Neste tutorial faremos o fine-tuning
+de um modelo pré-treinado com um framework de Deep Learning da sua escolha:
+
+* Fine-tuning de um modelo pré-treinado com o 🤗 Transformers [`Trainer`].
+* Fine-tuning de um modelo pré-treinado no TensorFlow com o Keras.
+* Fine-tuning de um modelo pré-treinado em PyTorch nativo.
+
+
+
+## Preparando um dataset
+
+
+
+Antes de aplicar o fine-tuning a um modelo pré-treinado, baixe um dataset e prepare-o para o treinamento.
+O tutorial anterior ensinará a processar os dados para o treinamento, e então poderá ter a oportunidade de testar
+esse novo conhecimento em algo prático.
+
+Comece carregando o dataset [Yelp Reviews](https://huggingface.co/datasets/yelp_review_full):
+
+```py
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("yelp_review_full")
+>>> dataset[100]
+{'label': 0,
+ 'text': 'My expectations for McDonalds are t rarely high. But for one to still fail so spectacularly...that takes something special!\\nThe cashier took my friends\'s order, then promptly ignored me. I had to force myself in front of a cashier who opened his register to wait on the person BEHIND me. I waited over five minutes for a gigantic order that included precisely one kid\'s meal. After watching two people who ordered after me be handed their food, I asked where mine was. The manager started yelling at the cashiers for \\"serving off their orders\\" when they didn\'t have their food. But neither cashier was anywhere near those controls, and the manager was the one serving food to customers and clearing the boards.\\nThe manager was rude when giving me my order. She didn\'t make sure that I had everything ON MY RECEIPT, and never even had the decency to apologize that I felt I was getting poor service.\\nI\'ve eaten at various McDonalds restaurants for over 30 years. I\'ve worked at more than one location. I expect bad days, bad moods, and the occasional mistake. But I have yet to have a decent experience at this store. It will remain a place I avoid unless someone in my party needs to avoid illness from low blood sugar. Perhaps I should go back to the racially biased service of Steak n Shake instead!'}
+```
+
+Como já sabe, é necessário ter um tokenizador para processar o texto e incluir uma estratégia de padding e truncamento,
+para manejar qualquer tamanho varíavel de sequência. Para processar o seu dataset em apenas um passo, utilize o método de
+🤗 Datasets [`map`](https://huggingface.co/docs/datasets/process#map) para aplicar uma função de preprocessamento sobre
+todo o dataset.
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-cased")
+
+
+>>> def tokenize_function(examples):
+... return tokenizer(examples["text"], padding="max_length", truncation=True)
+
+
+>>> tokenized_datasets = dataset.map(tokenize_function, batched=True)
+```
+
+Se desejar, é possível criar um subconjunto menor do dataset completo para aplicar o fine-tuning e assim reduzir o tempo necessário.
+
+```py
+>>> small_train_dataset = tokenized_datasets["train"].shuffle(seed=42).select(range(1000))
+>>> small_eval_dataset = tokenized_datasets["test"].shuffle(seed=42).select(range(1000))
+```
+
+
+
+## Fine-tuning com o `Trainer`
+
+
+
+O 🤗 Transformers proporciona uma classe [`Trainer`] otimizada para o treinamento de modelos de 🤗 Transformers,
+facilitando os primeiros passos do treinamento sem a necessidade de escrever manualmente o seu próprio ciclo.
+A API do [`Trainer`] suporta um grande conjunto de opções de treinamento e funcionalidades, como o logging,
+o gradient accumulation e o mixed precision.
+
+Comece carregando seu modelo e especifique o número de labels de previsão.
+A partir do [Card Dataset](https://huggingface.co/datasets/yelp_review_full#data-fields) do Yelp Reveiw, que ja
+sabemos ter 5 labels usamos o seguinte código:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-cased", num_labels=5)
+```
+
+
+
+ Você verá um alerta sobre alguns pesos pré-treinados que não estão sendo utilizados e que alguns pesos estão
+ sendo inicializados aleatoriamente. Não se preocupe, essa mensagem é completamente normal.
+ O header/cabeçário pré-treinado do modelo BERT é descartado e substitui-se por um header de classificação
+ inicializado aleatoriamente. Assim, pode aplicar o fine-tuning a este novo header do modelo em sua tarefa
+ de classificação de sequências fazendo um transfer learning do modelo pré-treinado.
+
+
+
+### Hiperparâmetros de treinamento
+
+Em seguida, crie uma classe [`TrainingArguments`] que contenha todos os hiperparâmetros que possam ser ajustados, assim
+como os indicadores para ativar as diferentes opções de treinamento. Para este tutorial, você pode começar o treinamento
+usando os [hiperparámetros](https://huggingface.co/docs/transformers/main_classes/trainer#transformers.TrainingArguments) padrão,
+porém, sinta-se livre para experimentar com eles e encontrar uma configuração ótima.
+
+Especifique onde salvar os checkpoints do treinamento:
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(output_dir="test_trainer")
+```
+
+### Métricas
+
+O [`Trainer`] não avalia automaticamente o rendimento do modelo durante o treinamento. Será necessário passar ao
+[`Trainer`] uma função para calcular e fazer um diagnóstico sobre as métricas. A biblioteca 🤗 Datasets proporciona
+uma função de [`accuracy`](https://huggingface.co/metrics/accuracy) simples que pode ser carregada com a função
+`load_metric` (ver este [tutorial](https://huggingface.co/docs/datasets/metrics) para mais informações):
+
+```py
+>>> import numpy as np
+>>> from datasets import load_metric
+
+>>> metric = load_metric("accuracy")
+```
+
+Defina a função `compute` dentro de `metric` para calcular a precisão das suas predições.
+Antes de passar as suas predições ao `compute`, é necessário converter as predições à logits (lembre-se que
+todos os modelos de 🤗 Transformers retornam logits).
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... predictions = np.argmax(logits, axis=-1)
+... return metric.compute(predictions=predictions, references=labels)
+```
+
+Se quiser controlar as suas métricas de avaliação durante o fine-tuning, especifique o parâmetro `eval_strategy`
+nos seus argumentos de treinamento para que o modelo considere a métrica de avaliação ao final de cada época:
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(output_dir="test_trainer", eval_strategy="epoch")
+```
+
+### Trainer
+
+Crie um objeto [`Trainer`] com o seu modelo, argumentos de treinamento, conjuntos de dados de treinamento e de teste, e a sua função de avaliação:
+
+```py
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=small_train_dataset,
+... eval_dataset=small_eval_dataset,
+... compute_metrics=compute_metrics,
+... )
+```
+
+Em seguida, aplique o fine-tuning a seu modelo chamado [`~transformers.Trainer.train`]:
+
+```py
+>>> trainer.train()
+```
+
+
+
+## Fine-tuning com Keras
+
+
+
+Os modelos de 🤗 Transformers também permitem realizar o treinamento com o TensorFlow com a API do Keras.
+Contudo, será necessário fazer algumas mudanças antes de realizar o fine-tuning.
+
+### Conversão do dataset ao formato do TensorFlow
+
+O [`DefaultDataCollator`] junta os tensores em um batch para que o modelo possa ser treinado em cima deles.
+Assegure-se de especificar os `return_tensors` para retornar os tensores do TensorFlow:
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+```
+
+
+
+ O [`Trainer`] utiliza [`DataCollatorWithPadding`] por padrão, então você não precisa especificar explicitamente um
+ colador de dados (data collator).
+
+
+
+Em seguida, converta os datasets tokenizados em datasets do TensorFlow com o método
+[`to_tf_dataset`](https://huggingface.co/docs/datasets/package_reference/main_classes#datasets.Dataset.to_tf_dataset).
+Especifique suas entradas em `columns` e seu rótulo em `label_cols`:
+
+```py
+>>> tf_train_dataset = small_train_dataset.to_tf_dataset(
+... columns=["attention_mask", "input_ids", "token_type_ids"],
+... label_cols="labels",
+... shuffle=True,
+... collate_fn=data_collator,
+... batch_size=8,
+... )
+
+>>> tf_validation_dataset = small_eval_dataset.to_tf_dataset(
+... columns=["attention_mask", "input_ids", "token_type_ids"],
+... label_cols="labels",
+... shuffle=False,
+... collate_fn=data_collator,
+... batch_size=8,
+... )
+```
+
+### Compilação e ajustes
+
+Carregue um modelo do TensorFlow com o número esperado de rótulos:
+
+```py
+>>> import tensorflow as tf
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-cased", num_labels=5)
+```
+
+A seguir, compile e ajuste o fine-tuning a seu modelo com [`fit`](https://keras.io/api/models/model_training_apis/) como
+faria com qualquer outro modelo do Keras:
+
+```py
+>>> model.compile(
+... optimizer=tf.keras.optimizers.Adam(learning_rate=5e-5),
+... loss=tf.keras.losses.SparseCategoricalCrossentropy(from_logits=True),
+... metrics=tf.metrics.SparseCategoricalAccuracy(),
+... )
+
+>>> model.fit(tf_train_dataset, validation_data=tf_validation_dataset, epochs=3)
+```
+
+
+
+## Fine-tune em PyTorch nativo
+
+
+
+O [`Trainer`] se encarrega do ciclo de treinamento e permite aplicar o fine-tuning a um modelo em uma linha de código apenas.
+Para os usuários que preferirem escrever o seu próprio ciclo de treinamento, também é possível aplicar o fine-tuning a um
+modelo de 🤗 Transformers em PyTorch nativo.
+
+Neste momento, talvez ocorra a necessidade de reinicar seu notebook ou executar a seguinte linha de código para liberar
+memória:
+
+```py
+del model
+del pytorch_model
+del trainer
+torch.cuda.empty_cache()
+```
+
+Em sequência, faremos um post-processing manual do `tokenized_dataset` e assim prepará-lo para o treinamento.
+
+1. Apague a coluna de `text` porque o modelo não aceita texto cru como entrada:
+
+ ```py
+ >>> tokenized_datasets = tokenized_datasets.remove_columns(["text"])
+ ```
+
+2. Troque o nome da coluna `label` para `labels`, pois o modelo espera um argumento de mesmo nome:
+
+ ```py
+ >>> tokenized_datasets = tokenized_datasets.rename_column("label", "labels")
+ ```
+
+3. Defina o formato do dataset para retornar tensores do PyTorch no lugar de listas:
+
+ ```py
+ >>> tokenized_datasets.set_format("torch")
+ ```
+
+Em sequência, crie um subconjunto menor do dataset, como foi mostrado anteriormente, para acelerá-lo o fine-tuning.
+
+```py
+>>> small_train_dataset = tokenized_datasets["train"].shuffle(seed=42).select(range(1000))
+>>> small_eval_dataset = tokenized_datasets["test"].shuffle(seed=42).select(range(1000))
+```
+
+### DataLoader
+
+Crie um `DataLoader` para os seus datasets de treinamento e de teste para poder iterar sobre batches de dados:
+
+```py
+>>> from torch.utils.data import DataLoader
+
+>>> train_dataloader = DataLoader(small_train_dataset, shuffle=True, batch_size=8)
+>>> eval_dataloader = DataLoader(small_eval_dataset, batch_size=8)
+```
+
+Carregue seu modelo com o número de labels esperados:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("google-bert/bert-base-cased", num_labels=5)
+```
+
+### Otimização e configuração do Learning Rate
+
+Crie um otimizador e um learning rate para aplicar o fine-tuning ao modelo.
+Iremos utilizar o otimizador [`AdamW`](https://pytorch.org/docs/stable/generated/torch.optim.AdamW.html) do PyTorch:
+
+```py
+>>> from torch.optim import AdamW
+
+>>> optimizer = AdamW(model.parameters(), lr=5e-5)
+```
+
+Defina o learning rate do [`Trainer`]:
+
+```py
+>>> from transformers import get_scheduler
+
+>>> num_epochs = 3
+>>> num_training_steps = num_epochs * len(train_dataloader)
+>>> lr_scheduler = get_scheduler(
+... name="linear", optimizer=optimizer, num_warmup_steps=0, num_training_steps=num_training_steps
+... )
+```
+
+Por último, especifique o `device` do ambiente para utilizar uma GPU se tiver acesso à alguma. Caso contrário, o treinamento
+em uma CPU pode acabar levando várias horas em vez de minutos.
+
+```py
+>>> import torch
+
+>>> device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+>>> model.to(device)
+```
+
+
+
+ Se necessário, você pode obter o acesso gratuito a uma GPU na núvem por meio de um notebook no
+ [Colaboratory](https://colab.research.google.com/) ou [SageMaker StudioLab](https://studiolab.sagemaker.aws/)
+ se não tiver esse recurso de forma local.
+
+
+
+Perfeito, agora estamos prontos para começar o treinamento! 🥳
+
+### Ciclo de treinamento
+
+Para visualizar melhor o processo de treinamento, utilize a biblioteca [tqdm](https://tqdm.github.io/) para adicionar
+uma barra de progresso sobre o número de passos percorridos no treinamento atual:
+
+```py
+>>> from tqdm.auto import tqdm
+
+>>> progress_bar = tqdm(range(num_training_steps))
+
+>>> model.train()
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... outputs = model(**batch)
+... loss = outputs.loss
+... loss.backward()
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+### Métricas
+
+Da mesma forma que é necessário adicionar uma função de avaliação ao [`Trainer`], é necessário fazer o mesmo quando
+escrevendo o próprio ciclo de treinamento. Contudo, em vez de calcular e retornar a métrica final de cada época,
+você deverá adicionar todos os batches com [`add_batch`](https://huggingface.co/docs/datasets/package_reference/main_classes?highlight=add_batch#datasets.Metric.add_batch)
+e calcular a métrica apenas no final.
+
+```py
+>>> metric = load_metric("accuracy")
+>>> model.eval()
+>>> for batch in eval_dataloader:
+... batch = {k: v.to(device) for k, v in batch.items()}
+... with torch.no_grad():
+... outputs = model(**batch)
+
+... logits = outputs.logits
+... predictions = torch.argmax(logits, dim=-1)
+... metric.add_batch(predictions=predictions, references=batch["labels"])
+
+>>> metric.compute()
+```
+
+
+
+## Recursos adicionais
+
+Para mais exemplos de fine-tuning acesse:
+
+- [🤗 Transformers Examples](https://github.com/huggingface/transformers/tree/main/examples) inclui scripts
+para treinas tarefas comuns de NLP em PyTorch e TensorFlow.
+
+- [🤗 Transformers Notebooks](notebooks) contém vários notebooks sobre como aplicar o fine-tuning a um modelo
+para tarefas específicas no PyTorch e TensorFlow.
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/te/_toctree.yml b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/te/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..5e6b45eb472f8dd998ddbaa3940d7fed96f12444
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/te/_toctree.yml
@@ -0,0 +1,6 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers
+ - local: quicktour
+ title: త్వరిత పర్యటన
+ title: ప్రారంభించడానికి
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/te/index.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/te/index.md
new file mode 100644
index 0000000000000000000000000000000000000000..3e23f8f5eb1392ff0f7fec76a606c625806b6ff7
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/te/index.md
@@ -0,0 +1,298 @@
+
+
+[పైటోర్చ్](https://pytorch.org/), [టెన్సర్ఫ్లో](https://www.tensorflow.org/), మరియు [జాక్స్](https://jax.readthedocs.io/en/latest/) కోసం స్థితి-కలాన యంత్ర అభ్యాసం.
+
+🤗 ట్రాన్స్ఫార్మర్స్ అభివృద్ధిస్తున్నది API మరియు ఉపకరణాలు, పూర్వ-చేతన మోడల్లను సులభంగా డౌన్లోడ్ మరియు శిక్షణ చేయడానికి అవసరమైన సమయం, వనరులు, మరియు వస్తువులను నుంచి మోడల్ను శీర్షికం నుంచి ప్రశిక్షించడం వరకు దేవాయనం చేస్తుంది. ఈ మోడల్లు విభిన్న మోడాలిటీలలో సాధారణ పనులకు మద్దతు చేస్తాయి, వంటివి:
+
+📝 **ప్రాకృతిక భాష ప్రక్రియ**: వచన వర్గీకరణ, పేరుల యొక్క యెంటిటీ గుర్తువు, ప్రశ్న సంవాద, భాషా రచన, సంక్షేపణ, అనువాదం, అనేక ప్రకారాలు, మరియు వచన సృష్టి.
+🖼️ **కంప్యూటర్ విషయం**: చిత్రం వర్గీకరణ, వస్త్రం గుర్తువు, మరియు విభజన.
+🗣️ **ఆడియో**: స్వయంచలన ప్రసంగాన్ని గుర్తుచేసేందుకు, ఆడియో వర్గీకరణ.
+🐙 **బహుమూలిక**: పట్టి ప్రశ్న సంవాద, ఆప్టికల్ సిఫర్ గుర్తువు, డాక్యుమెంట్లు స్క్యాన్ చేసినంతగా సమాచార పొందడం, వీడియో వర్గీకరణ, మరియు దృశ్య ప్రశ్న సంవాద.
+
+🤗 ట్రాన్స్ఫార్మర్స్ పైన మద్దతు చేస్తుంది పైన తొలగించడానికి పైన పైన పైన ప్రోగ్రామ్లో మోడల్ను శిక్షించండి, మరియు అన్ని ప్రాథమిక యొక్కడా ఇన్ఫరెన్స్ కోసం లోడ్ చేయండి. మో
+
+డల్లు కూడా ప్రొడక్షన్ వాతావరణాలలో వాడుకోవడానికి ONNX మరియు TorchScript వంటి ఆకృతులకు ఎగుమతి చేయవచ్చు.
+
+ఈరువులకు [హబ్](https://huggingface.co/models), [ఫోరం](https://discuss.huggingface.co/), లేదా [డిస్కార్డ్](https://discord.com/invite/JfAtkvEtRb) లో ఈ పెద్ద సముదాయంలో చేరండి!
+
+## మీరు హగ్గింగ్ ఫేస్ టీమ్ నుండి అనుకూల మద్దతు కోసం చూస్తున్నట్లయితే
+
+
+
+
+
+## విషయాలు
+
+డాక్యుమెంటేషన్ ఐదు విభాగాలుగా నిర్వహించబడింది:
+
+- **ప్రారంభించండి** లైబ్రరీ యొక్క శీఘ్ర పర్యటన మరియు రన్నింగ్ కోసం ఇన్స్టాలేషన్ సూచనలను అందిస్తుంది.
+- **ట్యుటోరియల్స్** మీరు అనుభవశూన్యుడు అయితే ప్రారంభించడానికి గొప్ప ప్రదేశం. మీరు లైబ్రరీని ఉపయోగించడం ప్రారంభించడానికి అవసరమైన ప్రాథమిక నైపుణ్యాలను పొందడానికి ఈ విభాగం మీకు సహాయం చేస్తుంది.
+- **హౌ-టు-గైడ్లు** లాంగ్వేజ్ మోడలింగ్ కోసం ప్రిట్రైన్డ్ మోడల్ని ఫైన్ట్యూన్ చేయడం లేదా కస్టమ్ మోడల్ను ఎలా వ్రాయాలి మరియు షేర్ చేయాలి వంటి నిర్దిష్ట లక్ష్యాన్ని ఎలా సాధించాలో మీకు చూపుతాయి.
+- **కాన్సెప్చువల్ గైడ్స్** మోడల్లు, టాస్క్లు మరియు 🤗 ట్రాన్స్ఫార్మర్ల డిజైన్ ఫిలాసఫీ వెనుక ఉన్న అంతర్లీన భావనలు మరియు ఆలోచనల గురించి మరింత చర్చ మరియు వివరణను అందిస్తుంది.
+- **API** అన్ని తరగతులు మరియు విధులను వివరిస్తుంది:
+
+ - **ప్రధాన తరగతులు** కాన్ఫిగరేషన్, మోడల్, టోకెనైజర్ మరియు పైప్లైన్ వంటి అత్యంత ముఖ్యమైన తరగతులను వివరిస్తుంది.
+ - **మోడల్స్** లైబ్రరీలో అమలు చేయబడిన ప్రతి మోడల్కు సంబంధించిన తరగతులు మరియు విధులను వివరిస్తుంది.
+ - **అంతర్గత సహాయకులు** అంతర్గతంగా ఉపయోగించే యుటిలిటీ క్లాస్లు మరియు ఫంక్షన్ల వివరాలు.
+
+## మద్దతు ఉన్న నమూనాలు మరియు ఫ్రేమ్వర్క్లు
+
+దిగువన ఉన్న పట్టిక ఆ ప్రతి మోడల్కు పైథాన్ కలిగి ఉన్నా లైబ్రరీలో ప్రస్తుత మద్దతును సూచిస్తుంది
+టోకెనైజర్ ("నెమ్మదిగా" అని పిలుస్తారు). Jax (ద్వారా
+ఫ్లాక్స్), పైటార్చ్ మరియు/లేదా టెన్సర్ఫ్లో.
+
+
+
+| Model | PyTorch support | TensorFlow support | Flax Support |
+|:------------------------------------------------------------------------:|:---------------:|:------------------:|:------------:|
+| [ALBERT](model_doc/albert) | ✅ | ✅ | ✅ |
+| [ALIGN](model_doc/align) | ✅ | ❌ | ❌ |
+| [AltCLIP](model_doc/altclip) | ✅ | ❌ | ❌ |
+| [Audio Spectrogram Transformer](model_doc/audio-spectrogram-transformer) | ✅ | ❌ | ❌ |
+| [Autoformer](model_doc/autoformer) | ✅ | ❌ | ❌ |
+| [Bark](model_doc/bark) | ✅ | ❌ | ❌ |
+| [BART](model_doc/bart) | ✅ | ✅ | ✅ |
+| [BARThez](model_doc/barthez) | ✅ | ✅ | ✅ |
+| [BARTpho](model_doc/bartpho) | ✅ | ✅ | ✅ |
+| [BEiT](model_doc/beit) | ✅ | ❌ | ✅ |
+| [BERT](model_doc/bert) | ✅ | ✅ | ✅ |
+| [Bert Generation](model_doc/bert-generation) | ✅ | ❌ | ❌ |
+| [BertJapanese](model_doc/bert-japanese) | ✅ | ✅ | ✅ |
+| [BERTweet](model_doc/bertweet) | ✅ | ✅ | ✅ |
+| [BigBird](model_doc/big_bird) | ✅ | ❌ | ✅ |
+| [BigBird-Pegasus](model_doc/bigbird_pegasus) | ✅ | ❌ | ❌ |
+| [BioGpt](model_doc/biogpt) | ✅ | ❌ | ❌ |
+| [BiT](model_doc/bit) | ✅ | ❌ | ❌ |
+| [Blenderbot](model_doc/blenderbot) | ✅ | ✅ | ✅ |
+| [BlenderbotSmall](model_doc/blenderbot-small) | ✅ | ✅ | ✅ |
+| [BLIP](model_doc/blip) | ✅ | ✅ | ❌ |
+| [BLIP-2](model_doc/blip-2) | ✅ | ❌ | ❌ |
+| [BLOOM](model_doc/bloom) | ✅ | ❌ | ✅ |
+| [BORT](model_doc/bort) | ✅ | ✅ | ✅ |
+| [BridgeTower](model_doc/bridgetower) | ✅ | ❌ | ❌ |
+| [BROS](model_doc/bros) | ✅ | ❌ | ❌ |
+| [ByT5](model_doc/byt5) | ✅ | ✅ | ✅ |
+| [CamemBERT](model_doc/camembert) | ✅ | ✅ | ❌ |
+| [CANINE](model_doc/canine) | ✅ | ❌ | ❌ |
+| [Chinese-CLIP](model_doc/chinese_clip) | ✅ | ❌ | ❌ |
+| [CLAP](model_doc/clap) | ✅ | ❌ | ❌ |
+| [CLIP](model_doc/clip) | ✅ | ✅ | ✅ |
+| [CLIPSeg](model_doc/clipseg) | ✅ | ❌ | ❌ |
+| [CodeGen](model_doc/codegen) | ✅ | ❌ | ❌ |
+| [CodeLlama](model_doc/code_llama) | ✅ | ❌ | ❌ |
+| [Conditional DETR](model_doc/conditional_detr) | ✅ | ❌ | ❌ |
+| [ConvBERT](model_doc/convbert) | ✅ | ✅ | ❌ |
+| [ConvNeXT](model_doc/convnext) | ✅ | ✅ | ❌ |
+| [ConvNeXTV2](model_doc/convnextv2) | ✅ | ❌ | ❌ |
+| [CPM](model_doc/cpm) | ✅ | ✅ | ✅ |
+| [CPM-Ant](model_doc/cpmant) | ✅ | ❌ | ❌ |
+| [CTRL](model_doc/ctrl) | ✅ | ✅ | ❌ |
+| [CvT](model_doc/cvt) | ✅ | ✅ | ❌ |
+| [Data2VecAudio](model_doc/data2vec) | ✅ | ❌ | ❌ |
+| [Data2VecText](model_doc/data2vec) | ✅ | ❌ | ❌ |
+| [Data2VecVision](model_doc/data2vec) | ✅ | ✅ | ❌ |
+| [DeBERTa](model_doc/deberta) | ✅ | ✅ | ❌ |
+| [DeBERTa-v2](model_doc/deberta-v2) | ✅ | ✅ | ❌ |
+| [Decision Transformer](model_doc/decision_transformer) | ✅ | ❌ | ❌ |
+| [Deformable DETR](model_doc/deformable_detr) | ✅ | ❌ | ❌ |
+| [DeiT](model_doc/deit) | ✅ | ✅ | ❌ |
+| [DePlot](model_doc/deplot) | ✅ | ❌ | ❌ |
+| [DETA](model_doc/deta) | ✅ | ❌ | ❌ |
+| [DETR](model_doc/detr) | ✅ | ❌ | ❌ |
+| [DialoGPT](model_doc/dialogpt) | ✅ | ✅ | ✅ |
+| [DiNAT](model_doc/dinat) | ✅ | ❌ | ❌ |
+| [DINOv2](model_doc/dinov2) | ✅ | ❌ | ❌ |
+| [DistilBERT](model_doc/distilbert) | ✅ | ✅ | ✅ |
+| [DiT](model_doc/dit) | ✅ | ❌ | ✅ |
+| [DonutSwin](model_doc/donut) | ✅ | ❌ | ❌ |
+| [DPR](model_doc/dpr) | ✅ | ✅ | ❌ |
+| [DPT](model_doc/dpt) | ✅ | ❌ | ❌ |
+| [EfficientFormer](model_doc/efficientformer) | ✅ | ✅ | ❌ |
+| [EfficientNet](model_doc/efficientnet) | ✅ | ❌ | ❌ |
+| [ELECTRA](model_doc/electra) | ✅ | ✅ | ✅ |
+| [EnCodec](model_doc/encodec) | ✅ | ❌ | ❌ |
+| [Encoder decoder](model_doc/encoder-decoder) | ✅ | ✅ | ✅ |
+| [ERNIE](model_doc/ernie) | ✅ | ❌ | ❌ |
+| [ErnieM](model_doc/ernie_m) | ✅ | ❌ | ❌ |
+| [ESM](model_doc/esm) | ✅ | ✅ | ❌ |
+| [FairSeq Machine-Translation](model_doc/fsmt) | ✅ | ❌ | ❌ |
+| [Falcon](model_doc/falcon) | ✅ | ❌ | ❌ |
+| [FLAN-T5](model_doc/flan-t5) | ✅ | ✅ | ✅ |
+| [FLAN-UL2](model_doc/flan-ul2) | ✅ | ✅ | ✅ |
+| [FlauBERT](model_doc/flaubert) | ✅ | ✅ | ❌ |
+| [FLAVA](model_doc/flava) | ✅ | ❌ | ❌ |
+| [FNet](model_doc/fnet) | ✅ | ❌ | ❌ |
+| [FocalNet](model_doc/focalnet) | ✅ | ❌ | ❌ |
+| [Funnel Transformer](model_doc/funnel) | ✅ | ✅ | ❌ |
+| [GIT](model_doc/git) | ✅ | ❌ | ❌ |
+| [GLPN](model_doc/glpn) | ✅ | ❌ | ❌ |
+| [GPT Neo](model_doc/gpt_neo) | ✅ | ❌ | ✅ |
+| [GPT NeoX](model_doc/gpt_neox) | ✅ | ❌ | ❌ |
+| [GPT NeoX Japanese](model_doc/gpt_neox_japanese) | ✅ | ❌ | ❌ |
+| [GPT-J](model_doc/gptj) | ✅ | ✅ | ✅ |
+| [GPT-Sw3](model_doc/gpt-sw3) | ✅ | ✅ | ✅ |
+| [GPTBigCode](model_doc/gpt_bigcode) | ✅ | ❌ | ❌ |
+| [GPTSAN-japanese](model_doc/gptsan-japanese) | ✅ | ❌ | ❌ |
+| [Graphormer](model_doc/graphormer) | ✅ | ❌ | ❌ |
+| [GroupViT](model_doc/groupvit) | ✅ | ✅ | ❌ |
+| [HerBERT](model_doc/herbert) | ✅ | ✅ | ✅ |
+| [Hubert](model_doc/hubert) | ✅ | ✅ | ❌ |
+| [I-BERT](model_doc/ibert) | ✅ | ❌ | ❌ |
+| [IDEFICS](model_doc/idefics) | ✅ | ❌ | ❌ |
+| [ImageGPT](model_doc/imagegpt) | ✅ | ❌ | ❌ |
+| [Informer](model_doc/informer) | ✅ | ❌ | ❌ |
+| [InstructBLIP](model_doc/instructblip) | ✅ | ❌ | ❌ |
+| [Jukebox](model_doc/jukebox) | ✅ | ❌ | ❌ |
+| [LayoutLM](model_doc/layoutlm) | ✅ | ✅ | ❌ |
+| [LayoutLMv2](model_doc/layoutlmv2) | ✅ | ❌ | ❌ |
+| [LayoutLMv3](model_doc/layoutlmv3) | ✅ | ✅ | ❌ |
+| [LayoutXLM](model_doc/layoutxlm) | ✅ | ❌ | ❌ |
+| [LED](model_doc/led) | ✅ | ✅ | ❌ |
+| [LeViT](model_doc/levit) | ✅ | ❌ | ❌ |
+| [LiLT](model_doc/lilt) | ✅ | ❌ | ❌ |
+| [LLaMA](model_doc/llama) | ✅ | ❌ | ❌ |
+| [Llama2](model_doc/llama2) | ✅ | ❌ | ❌ |
+| [Longformer](model_doc/longformer) | ✅ | ✅ | ❌ |
+| [LongT5](model_doc/longt5) | ✅ | ❌ | ✅ |
+| [LUKE](model_doc/luke) | ✅ | ❌ | ❌ |
+| [LXMERT](model_doc/lxmert) | ✅ | ✅ | ❌ |
+| [M-CTC-T](model_doc/mctct) | ✅ | ❌ | ❌ |
+| [M2M100](model_doc/m2m_100) | ✅ | ❌ | ❌ |
+| [Marian](model_doc/marian) | ✅ | ✅ | ✅ |
+| [MarkupLM](model_doc/markuplm) | ✅ | ❌ | ❌ |
+| [Mask2Former](model_doc/mask2former) | ✅ | ❌ | ❌ |
+| [MaskFormer](model_doc/maskformer) | ✅ | ❌ | ❌ |
+| [MatCha](model_doc/matcha) | ✅ | ❌ | ❌ |
+| [mBART](model_doc/mbart) | ✅ | ✅ | ✅ |
+| [mBART-50](model_doc/mbart50) | ✅ | ✅ | ✅ |
+| [MEGA](model_doc/mega) | ✅ | ❌ | ❌ |
+| [Megatron-BERT](model_doc/megatron-bert) | ✅ | ❌ | ❌ |
+| [Megatron-GPT2](model_doc/megatron_gpt2) | ✅ | ✅ | ✅ |
+| [MGP-STR](model_doc/mgp-str) | ✅ | ❌ | ❌ |
+| [Mistral](model_doc/mistral) | ✅ | ❌ | ❌ |
+| [mLUKE](model_doc/mluke) | ✅ | ❌ | ❌ |
+| [MMS](model_doc/mms) | ✅ | ✅ | ✅ |
+| [MobileBERT](model_doc/mobilebert) | ✅ | ✅ | ❌ |
+| [MobileNetV1](model_doc/mobilenet_v1) | ✅ | ❌ | ❌ |
+| [MobileNetV2](model_doc/mobilenet_v2) | ✅ | ❌ | ❌ |
+| [MobileViT](model_doc/mobilevit) | ✅ | ✅ | ❌ |
+| [MobileViTV2](model_doc/mobilevitv2) | ✅ | ❌ | ❌ |
+| [MPNet](model_doc/mpnet) | ✅ | ✅ | ❌ |
+| [MPT](model_doc/mpt) | ✅ | ❌ | ❌ |
+| [MRA](model_doc/mra) | ✅ | ❌ | ❌ |
+| [MT5](model_doc/mt5) | ✅ | ✅ | ✅ |
+| [MusicGen](model_doc/musicgen) | ✅ | ❌ | ❌ |
+| [MVP](model_doc/mvp) | ✅ | ❌ | ❌ |
+| [NAT](model_doc/nat) | ✅ | ❌ | ❌ |
+| [Nezha](model_doc/nezha) | ✅ | ❌ | ❌ |
+| [NLLB](model_doc/nllb) | ✅ | ❌ | ❌ |
+| [NLLB-MOE](model_doc/nllb-moe) | ✅ | ❌ | ❌ |
+| [Nougat](model_doc/nougat) | ✅ | ✅ | ✅ |
+| [Nyströmformer](model_doc/nystromformer) | ✅ | ❌ | ❌ |
+| [OneFormer](model_doc/oneformer) | ✅ | ❌ | ❌ |
+| [OpenAI GPT](model_doc/openai-gpt) | ✅ | ✅ | ❌ |
+| [OpenAI GPT-2](model_doc/gpt2) | ✅ | ✅ | ✅ |
+| [OpenLlama](model_doc/open-llama) | ✅ | ❌ | ❌ |
+| [OPT](model_doc/opt) | ✅ | ✅ | ✅ |
+| [OWL-ViT](model_doc/owlvit) | ✅ | ❌ | ❌ |
+| [Pegasus](model_doc/pegasus) | ✅ | ✅ | ✅ |
+| [PEGASUS-X](model_doc/pegasus_x) | ✅ | ❌ | ❌ |
+| [Perceiver](model_doc/perceiver) | ✅ | ❌ | ❌ |
+| [Persimmon](model_doc/persimmon) | ✅ | ❌ | ❌ |
+| [PhoBERT](model_doc/phobert) | ✅ | ✅ | ✅ |
+| [Pix2Struct](model_doc/pix2struct) | ✅ | ❌ | ❌ |
+| [PLBart](model_doc/plbart) | ✅ | ❌ | ❌ |
+| [PoolFormer](model_doc/poolformer) | ✅ | ❌ | ❌ |
+| [Pop2Piano](model_doc/pop2piano) | ✅ | ❌ | ❌ |
+| [ProphetNet](model_doc/prophetnet) | ✅ | ❌ | ❌ |
+| [PVT](model_doc/pvt) | ✅ | ❌ | ❌ |
+| [QDQBert](model_doc/qdqbert) | ✅ | ❌ | ❌ |
+| [RAG](model_doc/rag) | ✅ | ✅ | ❌ |
+| [REALM](model_doc/realm) | ✅ | ❌ | ❌ |
+| [Reformer](model_doc/reformer) | ✅ | ❌ | ❌ |
+| [RegNet](model_doc/regnet) | ✅ | ✅ | ✅ |
+| [RemBERT](model_doc/rembert) | ✅ | ✅ | ❌ |
+| [ResNet](model_doc/resnet) | ✅ | ✅ | ✅ |
+| [RetriBERT](model_doc/retribert) | ✅ | ❌ | ❌ |
+| [RoBERTa](model_doc/roberta) | ✅ | ✅ | ✅ |
+| [RoBERTa-PreLayerNorm](model_doc/roberta-prelayernorm) | ✅ | ✅ | ✅ |
+| [RoCBert](model_doc/roc_bert) | ✅ | ❌ | ❌ |
+| [RoFormer](model_doc/roformer) | ✅ | ✅ | ✅ |
+| [RWKV](model_doc/rwkv) | ✅ | ❌ | ❌ |
+| [SAM](model_doc/sam) | ✅ | ✅ | ❌ |
+| [SegFormer](model_doc/segformer) | ✅ | ✅ | ❌ |
+| [SEW](model_doc/sew) | ✅ | ❌ | ❌ |
+| [SEW-D](model_doc/sew-d) | ✅ | ❌ | ❌ |
+| [Speech Encoder decoder](model_doc/speech-encoder-decoder) | ✅ | ❌ | ✅ |
+| [Speech2Text](model_doc/speech_to_text) | ✅ | ✅ | ❌ |
+| [SpeechT5](model_doc/speecht5) | ✅ | ❌ | ❌ |
+| [Splinter](model_doc/splinter) | ✅ | ❌ | ❌ |
+| [SqueezeBERT](model_doc/squeezebert) | ✅ | ❌ | ❌ |
+| [SwiftFormer](model_doc/swiftformer) | ✅ | ❌ | ❌ |
+| [Swin Transformer](model_doc/swin) | ✅ | ✅ | ❌ |
+| [Swin Transformer V2](model_doc/swinv2) | ✅ | ❌ | ❌ |
+| [Swin2SR](model_doc/swin2sr) | ✅ | ❌ | ❌ |
+| [SwitchTransformers](model_doc/switch_transformers) | ✅ | ❌ | ❌ |
+| [T5](model_doc/t5) | ✅ | ✅ | ✅ |
+| [T5v1.1](model_doc/t5v1.1) | ✅ | ✅ | ✅ |
+| [Table Transformer](model_doc/table-transformer) | ✅ | ❌ | ❌ |
+| [TAPAS](model_doc/tapas) | ✅ | ✅ | ❌ |
+| [TAPEX](model_doc/tapex) | ✅ | ✅ | ✅ |
+| [Time Series Transformer](model_doc/time_series_transformer) | ✅ | ❌ | ❌ |
+| [TimeSformer](model_doc/timesformer) | ✅ | ❌ | ❌ |
+| [Trajectory Transformer](model_doc/trajectory_transformer) | ✅ | ❌ | ❌ |
+| [Transformer-XL](model_doc/transfo-xl) | ✅ | ✅ | ❌ |
+| [TrOCR](model_doc/trocr) | ✅ | ❌ | ❌ |
+| [TVLT](model_doc/tvlt) | ✅ | ❌ | ❌ |
+| [UL2](model_doc/ul2) | ✅ | ✅ | ✅ |
+| [UMT5](model_doc/umt5) | ✅ | ❌ | ❌ |
+| [UniSpeech](model_doc/unispeech) | ✅ | ❌ | ❌ |
+| [UniSpeechSat](model_doc/unispeech-sat) | ✅ | ❌ | ❌ |
+| [UPerNet](model_doc/upernet) | ✅ | ❌ | ❌ |
+| [VAN](model_doc/van) | ✅ | ❌ | ❌ |
+| [VideoMAE](model_doc/videomae) | ✅ | ❌ | ❌ |
+| [ViLT](model_doc/vilt) | ✅ | ❌ | ❌ |
+| [Vision Encoder decoder](model_doc/vision-encoder-decoder) | ✅ | ✅ | ✅ |
+| [VisionTextDualEncoder](model_doc/vision-text-dual-encoder) | ✅ | ✅ | ✅ |
+| [VisualBERT](model_doc/visual_bert) | ✅ | ❌ | ❌ |
+| [ViT](model_doc/vit) | ✅ | ✅ | ✅ |
+| [ViT Hybrid](model_doc/vit_hybrid) | ✅ | ❌ | ❌ |
+| [VitDet](model_doc/vitdet) | ✅ | ❌ | ❌ |
+| [ViTMAE](model_doc/vit_mae) | ✅ | ✅ | ❌ |
+| [ViTMatte](model_doc/vitmatte) | ✅ | ❌ | ❌ |
+| [ViTMSN](model_doc/vit_msn) | ✅ | ❌ | ❌ |
+| [VITS](model_doc/vits) | ✅ | ❌ | ❌ |
+| [ViViT](model_doc/vivit) | ✅ | ❌ | ❌ |
+| [Wav2Vec2](model_doc/wav2vec2) | ✅ | ✅ | ✅ |
+| [Wav2Vec2-Conformer](model_doc/wav2vec2-conformer) | ✅ | ❌ | ❌ |
+| [Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme) | ✅ | ✅ | ✅ |
+| [WavLM](model_doc/wavlm) | ✅ | ❌ | ❌ |
+| [Whisper](model_doc/whisper) | ✅ | ✅ | ✅ |
+| [X-CLIP](model_doc/xclip) | ✅ | ❌ | ❌ |
+| [X-MOD](model_doc/xmod) | ✅ | ❌ | ❌ |
+| [XGLM](model_doc/xglm) | ✅ | ✅ | ✅ |
+| [XLM](model_doc/xlm) | ✅ | ✅ | ❌ |
+| [XLM-ProphetNet](model_doc/xlm-prophetnet) | ✅ | ❌ | ❌ |
+| [XLM-RoBERTa](model_doc/xlm-roberta) | ✅ | ✅ | ✅ |
+| [XLM-RoBERTa-XL](model_doc/xlm-roberta-xl) | ✅ | ❌ | ❌ |
+| [XLM-V](model_doc/xlm-v) | ✅ | ✅ | ✅ |
+| [XLNet](model_doc/xlnet) | ✅ | ✅ | ❌ |
+| [XLS-R](model_doc/xls_r) | ✅ | ✅ | ✅ |
+| [XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2) | ✅ | ✅ | ✅ |
+| [YOLOS](model_doc/yolos) | ✅ | ❌ | ❌ |
+| [YOSO](model_doc/yoso) | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/te/quicktour.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/te/quicktour.md
new file mode 100644
index 0000000000000000000000000000000000000000..6045b673d2d3d0e71f097ff6666f3dd9bb9a5f06
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/te/quicktour.md
@@ -0,0 +1,557 @@
+
+
+# శీఘ్ర పర్యటన
+
+[[ఓపెన్-ఇన్-కోలాబ్]]
+
+🤗 ట్రాన్స్ఫార్మర్లతో లేచి పరుగెత్తండి! మీరు డెవలపర్ అయినా లేదా రోజువారీ వినియోగదారు అయినా, ఈ శీఘ్ర పర్యటన మీకు ప్రారంభించడానికి సహాయం చేస్తుంది మరియు [`pipeline`] అనుమితి కోసం ఎలా ఉపయోగించాలో మీకు చూపుతుంది, [AutoClass](./model_doc/auto) తో ప్రీట్రైన్డ్ మోడల్ మరియు ప్రిప్రాసెసర్/ ఆటో, మరియు PyTorch లేదా TensorFlowతో మోడల్కు త్వరగా శిక్షణ ఇవ్వండి. మీరు ఒక అనుభవశూన్యుడు అయితే, ఇక్కడ పరిచయం చేయబడిన భావనల గురించి మరింత లోతైన వివరణల కోసం మా ట్యుటోరియల్స్ లేదా [course](https://huggingface.co/course/chapter1/1)ని తనిఖీ చేయమని మేము సిఫార్సు చేస్తున్నాము.
+
+మీరు ప్రారంభించడానికి ముందు, మీరు అవసరమైన అన్ని లైబ్రరీలను ఇన్స్టాల్ చేశారని నిర్ధారించుకోండి:
+
+```bash
+!pip install transformers datasets evaluate accelerate
+```
+
+మీరు మీ ప్రాధాన్య యంత్ర అభ్యాస ఫ్రేమ్వర్క్ను కూడా ఇన్స్టాల్ చేయాలి:
+
+
+
+
+```bash
+pip install torch
+```
+
+
+
+```bash
+pip install tensorflow
+```
+
+
+
+## పైప్లైన్
+
+
+
+[`pipeline`] అనుమితి కోసం ముందుగా శిక్షణ పొందిన నమూనాను ఉపయోగించడానికి సులభమైన మరియు వేగవంతమైన మార్గం. మీరు వివిధ పద్ధతులలో అనేక పనుల కోసం [`pipeline`] వెలుపల ఉపయోగించవచ్చు, వాటిలో కొన్ని క్రింది పట్టికలో చూపబడ్డాయి:
+
+
+
+
+అందుబాటులో ఉన్న పనుల పూర్తి జాబితా కోసం, [పైప్లైన్ API సూచన](./main_classes/pipelines)ని తనిఖీ చేయండి.
+
+
+
+Here is the translation in Telugu:
+
+| **పని** | **వివరణ** | **మోడాలిటీ** | **పైప్లైన్ ఐడెంటిఫైయర్** |
+|------------------------------|--------------------------------------------------------------------------------------------------------|-----------------|------------------------------------------|
+| వచన వర్గీకరణు | కొన్ని వచనాల అంతా ఒక లేబుల్ను కొడి | NLP | pipeline(task=“sentiment-analysis”) |
+| వచన సృష్టి | ప్రమ్పుటం కలిగినంత వచనం సృష్టించండి | NLP | pipeline(task=“text-generation”) |
+| సంక్షేపణ | వచనం లేదా పత్రం కొరకు సంక్షేపణ తయారుచేసండి | NLP | pipeline(task=“summarization”) |
+| చిత్రం వర్గీకరణు | చిత్రంలో ఒక లేబుల్ను కొడి | కంప్యూటర్ విషయం | pipeline(task=“image-classification”) |
+| చిత్రం విభజన | ఒక చిత్రంలో ప్రతి వ్యక్తిగత పిక్సల్ను ఒక లేబుల్గా నమోదు చేయండి (సెమాంటిక్, పానొప్టిక్, మరియు ఇన్స్టన్స్ విభజనలను మద్దతు చేస్తుంది) | కంప్యూటర్ విషయం | pipeline(task=“image-segmentation”) |
+| వస్త్రం గుర్తువు | ఒక చిత్రంలో పదాల యొక్క బౌండింగ్ బాక్స్లను మరియు వస్త్రాల వర్గాలను అంచనా చేయండి | కంప్యూటర్ విషయం | pipeline(task=“object-detection”) |
+| ఆడియో గుర్తువు | కొన్ని ఆడియో డేటానికి ఒక లేబుల్ను కొడి | ఆడియో | pipeline(task=“audio-classification”) |
+| స్వయంచలన ప్రసంగ గుర్తువు | ప్రసంగాన్ని వచనంగా వర్ణించండి | ఆడియో | pipeline(task=“automatic-speech-recognition”) |
+| దృశ్య ప్రశ్న సంవాదం | వచనం మరియు ప్రశ్నను నమోదు చేసిన చిత్రంతో ప్రశ్నకు సమాధానం ఇవ్వండి | బహుమూలిక | pipeline(task=“vqa”) |
+| పత్రం ప్రశ్న సంవాదం | ప్రశ్నను పత్రం లేదా డాక్యుమెంట్తో సమాధానం ఇవ్వండి | బహుమూలిక | pipeline(task="document-question-answering") |
+| చిత్రం వ్రాసాయింగ్ | కొన్ని చిత్రానికి పిటియార్లను సృష్టించండి | బహుమూలిక | pipeline(task="image-to-text") |
+
+
+[`pipeline`] యొక్క ఉదాహరణను సృష్టించడం ద్వారా మరియు మీరు దానిని ఉపయోగించాలనుకుంటున్న పనిని పేర్కొనడం ద్వారా ప్రారంభించండి. ఈ గైడ్లో, మీరు సెంటిమెంట్ విశ్లేషణ కోసం [`pipeline`]ని ఉదాహరణగా ఉపయోగిస్తారు:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("sentiment-analysis")
+```
+
+సెంటిమెంట్ విశ్లేషణ కోసం [`pipeline`] డిఫాల్ట్ [ప్రీట్రైన్డ్ మోడల్](https://huggingface.co/distilbert/distilbert-base-uncased-finetuned-sst-2-english) మరియు టోకెనైజర్ని డౌన్లోడ్ చేస్తుంది మరియు కాష్ చేస్తుంది. ఇప్పుడు మీరు మీ లక్ష్య వచనంలో `classifier`ని ఉపయోగించవచ్చు:
+
+```py
+>>> classifier("We are very happy to show you the 🤗 Transformers library.")
+[{'label': 'POSITIVE', 'score': 0.9998}]
+```
+
+మీరు ఒకటి కంటే ఎక్కువ ఇన్పుట్లను కలిగి ఉంటే, నిఘంటువుల జాబితాను అందించడానికి మీ ఇన్పుట్లను జాబితాగా [`pipeline`]కి పంపండి:
+
+```py
+>>> results = classifier(["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."])
+>>> for result in results:
+... print(f"label: {result['label']}, with score: {round(result['score'], 4)}")
+label: POSITIVE, with score: 0.9998
+label: NEGATIVE, with score: 0.5309
+```
+
+[`pipeline`] మీకు నచ్చిన ఏదైనా పని కోసం మొత్తం డేటాసెట్ను కూడా పునరావృతం చేయగలదు. ఈ ఉదాహరణ కోసం, స్వయంచాలక ప్రసంగ గుర్తింపును మన పనిగా ఎంచుకుందాం:
+
+```py
+>>> import torch
+>>> from transformers import pipeline
+
+>>> speech_recognizer = pipeline("automatic-speech-recognition", model="facebook/wav2vec2-base-960h")
+```
+
+మీరు మళ్లీ మళ్లీ చెప్పాలనుకుంటున్న ఆడియో డేటాసెట్ను లోడ్ చేయండి (మరిన్ని వివరాల కోసం 🤗 డేటాసెట్లు [త్వరిత ప్రారంభం](https://huggingface.co/docs/datasets/quickstart#audio) చూడండి. ఉదాహరణకు, [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) డేటాసెట్ను లోడ్ చేయండి:
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train") # doctest: +IGNORE_RESULT
+```
+
+డేటాసెట్ యొక్క నమూనా రేటు నమూనాతో సరిపోలుతుందని మీరు నిర్ధారించుకోవాలి
+రేటు [`facebook/wav2vec2-base-960h`](https://huggingface.co/facebook/wav2vec2-base-960h) దీనిపై శిక్షణ పొందింది:
+
+```py
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=speech_recognizer.feature_extractor.sampling_rate))
+```
+
+`"ఆడియో"` కాలమ్కి కాల్ చేస్తున్నప్పుడు ఆడియో ఫైల్లు స్వయంచాలకంగా లోడ్ చేయబడతాయి మరియు మళ్లీ నమూనా చేయబడతాయి.
+మొదటి 4 నమూనాల నుండి ముడి వేవ్ఫార్మ్ శ్రేణులను సంగ్రహించి, పైప్లైన్కు జాబితాగా పాస్ చేయండి:
+
+```py
+>>> result = speech_recognizer(dataset[:4]["audio"])
+>>> print([d["text"] for d in result])
+['I WOULD LIKE TO SET UP A JOINT ACCOUNT WITH MY PARTNER HOW DO I PROCEED WITH DOING THAT', "FONDERING HOW I'D SET UP A JOIN TO HELL T WITH MY WIFE AND WHERE THE AP MIGHT BE", "I I'D LIKE TOY SET UP A JOINT ACCOUNT WITH MY PARTNER I'M NOT SEEING THE OPTION TO DO IT ON THE APSO I CALLED IN TO GET SOME HELP CAN I JUST DO IT OVER THE PHONE WITH YOU AND GIVE YOU THE INFORMATION OR SHOULD I DO IT IN THE AP AN I'M MISSING SOMETHING UQUETTE HAD PREFERRED TO JUST DO IT OVER THE PHONE OF POSSIBLE THINGS", 'HOW DO I FURN A JOINA COUT']
+```
+
+ఇన్పుట్లు పెద్దగా ఉన్న పెద్ద డేటాసెట్ల కోసం (స్పీచ్ లేదా విజన్ వంటివి), మెమరీలోని అన్ని ఇన్పుట్లను లోడ్ చేయడానికి మీరు జాబితాకు బదులుగా జెనరేటర్ను పాస్ చేయాలనుకుంటున్నారు. మరింత సమాచారం కోసం [పైప్లైన్ API సూచన](./main_classes/pipelines)ని చూడండి.
+
+### పైప్లైన్లో మరొక మోడల్ మరియు టోకెనైజర్ని ఉపయోగించండి
+
+[`pipeline`] [Hub](https://huggingface.co/models) నుండి ఏదైనా మోడల్ను కలిగి ఉంటుంది, దీని వలన ఇతర వినియోగ-కేసుల కోసం [`pipeline`]ని సులభంగా స్వీకరించవచ్చు. ఉదాహరణకు, మీరు ఫ్రెంచ్ టెక్స్ట్ను హ్యాండిల్ చేయగల మోడల్ కావాలనుకుంటే, తగిన మోడల్ కోసం ఫిల్టర్ చేయడానికి హబ్లోని ట్యాగ్లను ఉపయోగించండి. అగ్ర ఫిల్టర్ చేసిన ఫలితం మీరు ఫ్రెంచ్ టెక్స్ట్ కోసం ఉపయోగించగల సెంటిమెంట్ విశ్లేషణ కోసం ఫైన్ట్యూన్ చేయబడిన బహుభాషా [BERT మోడల్](https://huggingface.co/nlptown/bert-base-multilingual-uncased-sentiment)ని అందిస్తుంది:
+
+```py
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+```
+
+
+
+ముందుగా శిక్షణ పొందిన మోడల్ను లోడ్ చేయడానికి [`AutoModelForSequenceClassification`] మరియు [`AutoTokenizer`]ని ఉపయోగించండి మరియు దాని అనుబంధిత టోకెనైజర్ (తదుపరి విభాగంలో `AutoClass`పై మరిన్ని):
+
+```py
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+ముందుగా శిక్షణ పొందిన మోడల్ను లోడ్ చేయడానికి [`TFAutoModelForSequenceClassification`] మరియు [`AutoTokenizer`]ని ఉపయోగించండి మరియు దాని అనుబంధిత టోకెనైజర్ (తదుపరి విభాగంలో `TFAutoClass`పై మరిన్ని):
+
+```py
+>>> from transformers import AutoTokenizer, TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+
+
+[`pipeline`]లో మోడల్ మరియు టోకెనైజర్ను పేర్కొనండి మరియు ఇప్పుడు మీరు ఫ్రెంచ్ టెక్స్ట్పై `క్లాసిఫైయర్`ని వర్తింపజేయవచ్చు:
+
+```py
+>>> classifier = pipeline("sentiment-analysis", model=model, tokenizer=tokenizer)
+>>> classifier("Nous sommes très heureux de vous présenter la bibliothèque 🤗 Transformers.")
+[{'label': '5 stars', 'score': 0.7273}]
+```
+
+మీరు మీ వినియోగ-కేస్ కోసం మోడల్ను కనుగొనలేకపోతే, మీరు మీ డేటాపై ముందుగా శిక్షణ పొందిన మోడల్ను చక్కగా మార్చాలి. ఎలాగో తెలుసుకోవడానికి మా [ఫైన్ట్యూనింగ్ ట్యుటోరియల్](./training)ని చూడండి. చివరగా, మీరు మీ ప్రీట్రైన్డ్ మోడల్ని ఫైన్ట్యూన్ చేసిన తర్వాత, దయచేసి అందరి కోసం మెషిన్ లెర్నింగ్ని డెమోక్రటైజ్ చేయడానికి హబ్లోని సంఘంతో మోడల్ను [షేరింగ్](./model_sharing) పరిగణించండి! 🤗
+
+## AutoClass
+
+
+
+హుడ్ కింద, మీరు పైన ఉపయోగించిన [`pipeline`]కి శక్తిని అందించడానికి [`AutoModelForSequenceClassification`] మరియు [`AutoTokenizer`] తరగతులు కలిసి పని చేస్తాయి. ఒక [AutoClass](./model_doc/auto) అనేది ముందుగా శిక్షణ పొందిన మోడల్ యొక్క ఆర్కిటెక్చర్ను దాని పేరు లేదా మార్గం నుండి స్వయంచాలకంగా తిరిగి పొందే సత్వరమార్గం. మీరు మీ టాస్క్ కోసం తగిన `ఆటోక్లాస్`ని మాత్రమే ఎంచుకోవాలి మరియు ఇది అనుబంధిత ప్రీప్రాసెసింగ్ క్లాస్.
+
+మునుపటి విభాగం నుండి ఉదాహరణకి తిరిగి వెళ్లి, [`pipeline`] ఫలితాలను ప్రతిబింబించడానికి మీరు `ఆటోక్లాస్`ని ఎలా ఉపయోగించవచ్చో చూద్దాం.
+
+### AutoTokenizer
+
+ఒక మోడల్కు ఇన్పుట్లుగా సంఖ్యల శ్రేణిలో వచనాన్ని ప్రీప్రాసెసింగ్ చేయడానికి టోకెనైజర్ బాధ్యత వహిస్తుంది. పదాన్ని ఎలా విభజించాలి మరియు ఏ స్థాయిలో పదాలను విభజించాలి ([tokenizer సారాంశం](./tokenizer_summary)లో టోకనైజేషన్ గురించి మరింత తెలుసుకోండి) సహా టోకనైజేషన్ ప్రక్రియను నియంత్రించే అనేక నియమాలు ఉన్నాయి. గుర్తుంచుకోవలసిన ముఖ్యమైన విషయం ఏమిటంటే, మీరు మోడల్కు ముందే శిక్షణ పొందిన అదే టోకనైజేషన్ నియమాలను ఉపయోగిస్తున్నారని నిర్ధారించుకోవడానికి మీరు అదే మోడల్ పేరుతో టోకెనైజర్ను తక్షణం చేయాలి.
+
+[`AutoTokenizer`]తో టోకెనైజర్ను లోడ్ చేయండి:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tokenizer = AutoTokenizer.from_pretrained(model_name)
+```
+
+మీ వచనాన్ని టోకెనైజర్కు పంపండి:
+
+```py
+>>> encoding = tokenizer("We are very happy to show you the 🤗 Transformers library.")
+>>> print(encoding)
+{'input_ids': [101, 11312, 10320, 12495, 19308, 10114, 11391, 10855, 10103, 100, 58263, 13299, 119, 102],
+ 'token_type_ids': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'attention_mask': [1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1]}
+```
+
+టోకెనైజర్ వీటిని కలిగి ఉన్న నిఘంటువుని అందిస్తుంది:
+
+* [input_ids](./glossary#input-ids): మీ టోకెన్ల సంఖ్యాపరమైన ప్రాతినిధ్యం.
+* [అటెన్షన్_మాస్క్](./glossary#attention-mask): ఏ టోకెన్లకు హాజరు కావాలో సూచిస్తుంది.
+
+ఒక టోకెనైజర్ ఇన్పుట్ల జాబితాను కూడా ఆమోదించగలదు మరియు ఏకరీతి పొడవుతో బ్యాచ్ను తిరిగి ఇవ్వడానికి టెక్స్ట్ను ప్యాడ్ చేసి కత్తిరించవచ్చు:
+
+
+
+
+```py
+>>> pt_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="pt",
+... )
+```
+
+
+
+```py
+>>> tf_batch = tokenizer(
+... ["We are very happy to show you the 🤗 Transformers library.", "We hope you don't hate it."],
+... padding=True,
+... truncation=True,
+... max_length=512,
+... return_tensors="tf",
+... )
+```
+
+
+
+
+
+టోకనైజేషన్ గురించి మరిన్ని వివరాల కోసం [ప్రీప్రాసెస్](./preprocessing) ట్యుటోరియల్ని చూడండి మరియు ఇమేజ్, ఆడియో మరియు మల్టీమోడల్ ఇన్పుట్లను ప్రీప్రాసెస్ చేయడానికి [`AutoImageProcessor`], [`AutoFeatureExtractor`] మరియు [`AutoProcessor`] ఎలా ఉపయోగించాలి.
+
+
+
+### AutoModel
+
+
+
+🤗 ట్రాన్స్ఫార్మర్లు ప్రీట్రైన్డ్ ఇన్స్టాన్స్లను లోడ్ చేయడానికి సులభమైన మరియు ఏకీకృత మార్గాన్ని అందిస్తాయి. దీని అర్థం మీరు [`AutoTokenizer`]ని లోడ్ చేసినట్లుగా [`AutoModel`]ని లోడ్ చేయవచ్చు. టాస్క్ కోసం సరైన [`AutoModel`]ని ఎంచుకోవడం మాత్రమే తేడా. టెక్స్ట్ (లేదా సీక్వెన్స్) వర్గీకరణ కోసం, మీరు [`AutoModelForSequenceClassification`]ని లోడ్ చేయాలి:
+
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+[`AutoModel`] క్లాస్ ద్వారా సపోర్ట్ చేసే టాస్క్ల కోసం [టాస్క్ సారాంశం](./task_summary)ని చూడండి.
+
+
+
+ఇప్పుడు మీ ప్రీప్రాసెస్ చేయబడిన బ్యాచ్ ఇన్పుట్లను నేరుగా మోడల్కి పంపండి. మీరు `**`ని జోడించడం ద్వారా నిఘంటువుని అన్ప్యాక్ చేయాలి:
+
+```py
+>>> pt_outputs = pt_model(**pt_batch)
+```
+
+మోడల్ తుది యాక్టివేషన్లను `logits` లక్షణంలో అవుట్పుట్ చేస్తుంది. సంభావ్యతలను తిరిగి పొందడానికి సాఫ్ట్మాక్స్ ఫంక్షన్ను `logits` కు వర్తింపజేయండి:
+
+
+```py
+>>> from torch import nn
+
+>>> pt_predictions = nn.functional.softmax(pt_outputs.logits, dim=-1)
+>>> print(pt_predictions)
+tensor([[0.0021, 0.0018, 0.0115, 0.2121, 0.7725],
+ [0.2084, 0.1826, 0.1969, 0.1755, 0.2365]], grad_fn=)
+```
+
+
+
+🤗 ట్రాన్స్ఫార్మర్లు ప్రీట్రైన్డ్ ఇన్స్టాన్స్లను లోడ్ చేయడానికి సులభమైన మరియు ఏకీకృత మార్గాన్ని అందిస్తాయి. మీరు [`AutoTokenizer`]ని లోడ్ చేసినట్లుగా మీరు [`TFAutoModel`]ని లోడ్ చేయవచ్చని దీని అర్థం. టాస్క్ కోసం సరైన [`TFAutoModel`]ని ఎంచుకోవడం మాత్రమే తేడా. టెక్స్ట్ (లేదా సీక్వెన్స్) వర్గీకరణ కోసం, మీరు [`TFAutoModelForSequenceClassification`]ని లోడ్ చేయాలి:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model_name = "nlptown/bert-base-multilingual-uncased-sentiment"
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(model_name)
+```
+
+
+
+[`AutoModel`] క్లాస్ ద్వారా సపోర్ట్ చేసే టాస్క్ల కోసం [టాస్క్ సారాంశం](./task_summary)ని చూడండి.
+
+
+
+ఇప్పుడు మీ ప్రీప్రాసెస్ చేయబడిన బ్యాచ్ ఇన్పుట్లను నేరుగా మోడల్కి పంపండి. మీరు టెన్సర్లను ఇలా పాస్ చేయవచ్చు:
+
+```py
+>>> tf_outputs = tf_model(tf_batch)
+```
+
+మోడల్ తుది యాక్టివేషన్లను `logits` లక్షణంలో అవుట్పుట్ చేస్తుంది. సంభావ్యతలను తిరిగి పొందడానికి సాఫ్ట్మాక్స్ ఫంక్షన్ను `logits`కు వర్తింపజేయండి:
+
+```py
+>>> import tensorflow as tf
+
+>>> tf_predictions = tf.nn.softmax(tf_outputs.logits, axis=-1)
+>>> tf_predictions # doctest: +IGNORE_RESULT
+```
+
+
+
+
+
+అన్ని 🤗 ట్రాన్స్ఫార్మర్స్ మోడల్లు (PyTorch లేదా TensorFlow) తుది యాక్టివేషన్కు *ముందు* టెన్సర్లను అవుట్పుట్ చేస్తాయి
+ఫంక్షన్ (softmax వంటిది) ఎందుకంటే చివరి యాక్టివేషన్ ఫంక్షన్ తరచుగా నష్టంతో కలిసిపోతుంది. మోడల్ అవుట్పుట్లు ప్రత్యేక డేటాక్లాస్లు కాబట్టి వాటి లక్షణాలు IDEలో స్వయంచాలకంగా పూర్తి చేయబడతాయి. మోడల్ అవుట్పుట్లు టుపుల్ లేదా డిక్షనరీ లాగా ప్రవర్తిస్తాయి (మీరు పూర్ణాంకం, స్లైస్ లేదా స్ట్రింగ్తో ఇండెక్స్ చేయవచ్చు) ఈ సందర్భంలో, ఏదీ లేని గుణాలు విస్మరించబడతాయి.
+
+
+
+### మోడల్ను సేవ్ చేయండి
+
+
+
+మీ మోడల్ చక్కగా ట్యూన్ చేయబడిన తర్వాత, మీరు దానిని [`PreTrainedModel.save_pretrained`]ని ఉపయోగించి దాని టోకెనైజర్తో సేవ్ చేయవచ్చు:
+
+```py
+>>> pt_save_directory = "./pt_save_pretrained"
+>>> tokenizer.save_pretrained(pt_save_directory) # doctest: +IGNORE_RESULT
+>>> pt_model.save_pretrained(pt_save_directory)
+```
+
+మీరు మోడల్ని మళ్లీ ఉపయోగించడానికి సిద్ధంగా ఉన్నప్పుడు, దాన్ని [`PreTrainedModel.from_pretrained`]తో రీలోడ్ చేయండి:
+
+```py
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained("./pt_save_pretrained")
+```
+
+
+మీ మోడల్ చక్కగా ట్యూన్ చేయబడిన తర్వాత, మీరు దానిని [`TFPreTrainedModel.save_pretrained`]ని ఉపయోగించి దాని టోకెనైజర్తో సేవ్ చేయవచ్చు:
+
+```py
+>>> tf_save_directory = "./tf_save_pretrained"
+>>> tokenizer.save_pretrained(tf_save_directory) # doctest: +IGNORE_RESULT
+>>> tf_model.save_pretrained(tf_save_directory)
+```
+మీరు మోడల్ని మళ్లీ ఉపయోగించడానికి సిద్ధంగా ఉన్నప్పుడు, దాన్ని [`TFPreTrainedModel.from_pretrained`]తో రీలోడ్ చేయండి:
+
+```py
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained("./tf_save_pretrained")
+```
+
+
+
+ఒక ప్రత్యేకించి అద్భుతమైన 🤗 ట్రాన్స్ఫార్మర్స్ ఫీచర్ మోడల్ను సేవ్ చేయగల సామర్థ్యం మరియు దానిని PyTorch లేదా TensorFlow మోడల్గా రీలోడ్ చేయగలదు. `from_pt` లేదా `from_tf` పరామితి మోడల్ను ఒక ఫ్రేమ్వర్క్ నుండి మరొక ఫ్రేమ్వర్క్కి మార్చగలదు:
+
+
+
+
+```py
+>>> from transformers import AutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(pt_save_directory)
+>>> pt_model = AutoModelForSequenceClassification.from_pretrained(pt_save_directory, from_pt=True)
+```
+
+
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> tokenizer = AutoTokenizer.from_pretrained(tf_save_directory)
+>>> tf_model = TFAutoModelForSequenceClassification.from_pretrained(tf_save_directory, from_tf=True)
+```
+
+
+
+## కస్టమ్ మోడల్ బిల్డ్స్
+మోడల్ ఎలా నిర్మించబడుతుందో మార్చడానికి మీరు మోడల్ కాన్ఫిగరేషన్ క్లాస్ని సవరించవచ్చు. దాచిన లేయర్లు లేదా అటెన్షన్ హెడ్ల సంఖ్య వంటి మోడల్ లక్షణాలను కాన్ఫిగరేషన్ నిర్దేశిస్తుంది. మీరు కస్టమ్ కాన్ఫిగరేషన్ క్లాస్ నుండి మోడల్ను ప్రారంభించినప్పుడు మీరు మొదటి నుండి ప్రారంభిస్తారు. మోడల్ అట్రిబ్యూట్లు యాదృచ్ఛికంగా ప్రారంభించబడ్డాయి మరియు అర్థవంతమైన ఫలితాలను పొందడానికి మీరు మోడల్ను ఉపయోగించే ముందు దానికి శిక్షణ ఇవ్వాలి.
+
+[`AutoConfig`]ని దిగుమతి చేయడం ద్వారా ప్రారంభించండి, ఆపై మీరు సవరించాలనుకుంటున్న ప్రీట్రైన్డ్ మోడల్ను లోడ్ చేయండి. [`AutoConfig.from_pretrained`]లో, మీరు అటెన్షన్ హెడ్ల సంఖ్య వంటి మీరు మార్చాలనుకుంటున్న లక్షణాన్ని పేర్కొనవచ్చు:
+
+```py
+>>> from transformers import AutoConfig
+
+>>> my_config = AutoConfig.from_pretrained("distilbert/distilbert-base-uncased", n_heads=12)
+```
+
+
+
+[`AutoModel.from_config`]తో మీ అనుకూల కాన్ఫిగరేషన్ నుండి మోడల్ను సృష్టించండి:
+
+```py
+>>> from transformers import AutoModel
+
+>>> my_model = AutoModel.from_config(my_config)
+```
+
+
+[`TFAutoModel.from_config`]తో మీ అనుకూల కాన్ఫిగరేషన్ నుండి మోడల్ను సృష్టించండి:
+
+```py
+>>> from transformers import TFAutoModel
+
+>>> my_model = TFAutoModel.from_config(my_config)
+```
+
+
+
+అనుకూల కాన్ఫిగరేషన్లను రూపొందించడం గురించి మరింత సమాచారం కోసం [కస్టమ్ ఆర్కిటెక్చర్ని సృష్టించండి](./create_a_model) గైడ్ను చూడండి.
+
+## శిక్షకుడు - పైటార్చ్ ఆప్టిమైజ్ చేసిన శిక్షణ లూప్
+
+అన్ని మోడల్లు ప్రామాణికమైన [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module) కాబట్టి మీరు వాటిని ఏదైనా సాధారణ శిక్షణ లూప్లో ఉపయోగించవచ్చు. మీరు మీ స్వంత శిక్షణ లూప్ను వ్రాయగలిగినప్పటికీ, 🤗 ట్రాన్స్ఫార్మర్లు PyTorch కోసం [`ట్రైనర్`] తరగతిని అందజేస్తాయి, ఇందులో ప్రాథమిక శిక్షణ లూప్ ఉంటుంది మరియు పంపిణీ చేయబడిన శిక్షణ, మిశ్రమ ఖచ్చితత్వం మరియు మరిన్ని వంటి ఫీచర్ల కోసం అదనపు కార్యాచరణను జోడిస్తుంది.
+
+మీ విధిని బట్టి, మీరు సాధారణంగా కింది పారామితులను [`ట్రైనర్`]కి పంపుతారు:
+
+1. మీరు [`PreTrainedModel`] లేదా [`torch.nn.Module`](https://pytorch.org/docs/stable/nn.html#torch.nn.Module)తో ప్రారంభిస్తారు:
+ ```py
+ >>> from transformers import AutoModelForSequenceClassification
+
+ >>> model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. [`TrainingArguments`] మీరు నేర్చుకునే రేటు, బ్యాచ్ పరిమాణం మరియు శిక్షణ పొందవలసిన యుగాల సంఖ్య వంటి మార్చగల మోడల్ హైపర్పారామీటర్లను కలిగి ఉంది. మీరు ఎలాంటి శిక్షణా వాదనలను పేర్కొనకుంటే డిఫాల్ట్ విలువలు ఉపయోగించబడతాయి:
+
+ ```py
+ >>> from transformers import TrainingArguments
+
+ >>> training_args = TrainingArguments(
+ ... output_dir="path/to/save/folder/",
+ ... learning_rate=2e-5,
+ ... per_device_train_batch_size=8,
+ ... per_device_eval_batch_size=8,
+ ... num_train_epochs=2,
+ ... )
+ ```
+
+3. టోకెనైజర్, ఇమేజ్ ప్రాసెసర్, ఫీచర్ ఎక్స్ట్రాక్టర్ లేదా ప్రాసెసర్ వంటి ప్రీప్రాసెసింగ్ క్లాస్ని లోడ్ చేయండి:
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+4. డేటాసెట్ను లోడ్ చేయండి:
+
+ ```py
+ >>> from datasets import load_dataset
+
+ >>> dataset = load_dataset("rotten_tomatoes") # doctest: +IGNORE_RESULT
+ ```
+
+5. డేటాసెట్ను టోకనైజ్ చేయడానికి ఒక ఫంక్షన్ను సృష్టించండి:
+
+ ```py
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"])
+ ```
+
+ ఆపై దానిని [`~datasets.Dataset.map`]తో మొత్తం డేటాసెట్లో వర్తింపజేయండి:
+
+ ```py
+ >>> dataset = dataset.map(tokenize_dataset, batched=True)
+ ```
+
+6. మీ డేటాసెట్ నుండి ఉదాహరణల సమూహాన్ని సృష్టించడానికి [`DataCollatorWithPadding`]:
+
+ ```py
+ >>> from transformers import DataCollatorWithPadding
+
+ >>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+ ```
+
+ఇప్పుడు ఈ తరగతులన్నింటినీ [`Trainer`]లో సేకరించండి:
+
+```py
+>>> from transformers import Trainer
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=dataset["train"],
+... eval_dataset=dataset["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... ) # doctest: +SKIP
+```
+
+మీరు సిద్ధంగా ఉన్నప్పుడు, శిక్షణను ప్రారంభించడానికి [`~Trainer.train`]కి కాల్ చేయండి:
+
+```py
+>>> trainer.train() # doctest: +SKIP
+```
+
+
+
+సీక్వెన్స్-టు-సీక్వెన్స్ మోడల్ని ఉపయోగించే - అనువాదం లేదా సారాంశం వంటి పనుల కోసం, బదులుగా [`Seq2SeqTrainer`] మరియు [`Seq2SeqTrainingArguments`] తరగతులను ఉపయోగించండి.
+
+
+
+మీరు [`Trainer`] లోపల ఉన్న పద్ధతులను ఉపవర్గీకరించడం ద్వారా శిక్షణ లూప్ ప్రవర్తనను అనుకూలీకరించవచ్చు. ఇది లాస్ ఫంక్షన్, ఆప్టిమైజర్ మరియు షెడ్యూలర్ వంటి లక్షణాలను అనుకూలీకరించడానికి మిమ్మల్ని అనుమతిస్తుంది. ఉపవర్గీకరించబడే పద్ధతుల కోసం [`Trainer`] సూచనను పరిశీలించండి.
+
+శిక్షణ లూప్ను అనుకూలీకరించడానికి మరొక మార్గం [కాల్బ్యాక్లు](./main_classes/callback). మీరు ఇతర లైబ్రరీలతో అనుసంధానం చేయడానికి కాల్బ్యాక్లను ఉపయోగించవచ్చు మరియు పురోగతిపై నివేదించడానికి శిక్షణ లూప్ను తనిఖీ చేయవచ్చు లేదా శిక్షణను ముందుగానే ఆపవచ్చు. శిక్షణ లూప్లోనే కాల్బ్యాక్లు దేనినీ సవరించవు. లాస్ ఫంక్షన్ వంటివాటిని అనుకూలీకరించడానికి, మీరు బదులుగా [`Trainer`]ని ఉపవర్గం చేయాలి.
+
+## TensorFlowతో శిక్షణ పొందండి
+
+అన్ని మోడల్లు ప్రామాణికమైన [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model) కాబట్టి వాటిని [Keras]తో TensorFlowలో శిక్షణ పొందవచ్చు(https: //keras.io/) API. 🤗 ట్రాన్స్ఫార్మర్లు మీ డేటాసెట్ని సులభంగా `tf.data.Dataset`గా లోడ్ చేయడానికి [`~TFPreTrainedModel.prepare_tf_dataset`] పద్ధతిని అందజేస్తుంది కాబట్టి మీరు వెంటనే Keras' [`compile`](https://keras.io/api/models/model_training_apis/#compile-method) మరియు [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) పద్ధతులు.
+
+1. మీరు [`TFPreTrainedModel`] లేదా [`tf.keras.Model`](https://www.tensorflow.org/api_docs/python/tf/keras/Model)తో ప్రారంభిస్తారు:
+ ```py
+ >>> from transformers import TFAutoModelForSequenceClassification
+
+ >>> model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+2. టోకెనైజర్, ఇమేజ్ ప్రాసెసర్, ఫీచర్ ఎక్స్ట్రాక్టర్ లేదా ప్రాసెసర్ వంటి ప్రీప్రాసెసింగ్ క్లాస్ని లోడ్ చేయండి:
+
+ ```py
+ >>> from transformers import AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+ ```
+
+3. డేటాసెట్ను టోకనైజ్ చేయడానికి ఒక ఫంక్షన్ను సృష్టించండి:
+
+ ```py
+ >>> def tokenize_dataset(dataset):
+ ... return tokenizer(dataset["text"]) # doctest: +SKIP
+ ```
+
+4. [`~datasets.Dataset.map`]తో మొత్తం డేటాసెట్పై టోకెనైజర్ని వర్తింపజేయి, ఆపై డేటాసెట్ మరియు టోకెనైజర్ను [`~TFPreTrainedModel.prepare_tf_dataset`]కి పంపండి. మీరు కావాలనుకుంటే బ్యాచ్ పరిమాణాన్ని కూడా మార్చవచ్చు మరియు డేటాసెట్ను ఇక్కడ షఫుల్ చేయవచ్చు:
+ ```py
+ >>> dataset = dataset.map(tokenize_dataset) # doctest: +SKIP
+ >>> tf_dataset = model.prepare_tf_dataset(
+ ... dataset["train"], batch_size=16, shuffle=True, tokenizer=tokenizer
+ ... ) # doctest: +SKIP
+ ```
+
+5. మీరు సిద్ధంగా ఉన్నప్పుడు, శిక్షణను ప్రారంభించడానికి మీరు `కంపైల్` మరియు `ఫిట్`కి కాల్ చేయవచ్చు. ట్రాన్స్ఫార్మర్స్ మోడల్స్ అన్నీ డిఫాల్ట్ టాస్క్-సంబంధిత లాస్ ఫంక్షన్ని కలిగి ఉన్నాయని గుర్తుంచుకోండి, కాబట్టి మీరు కోరుకునే వరకు మీరు ఒకదానిని పేర్కొనవలసిన అవసరం లేదు:
+
+ ```py
+ >>> from tensorflow.keras.optimizers import Adam
+
+ >>> model.compile(optimizer=Adam(3e-5)) # No loss argument!
+ >>> model.fit(tf_dataset) # doctest: +SKIP
+ ```
+
+## తరవాత ఏంటి?
+
+ఇప్పుడు మీరు 🤗 ట్రాన్స్ఫార్మర్స్ త్వరిత పర్యటనను పూర్తి చేసారు, మా గైడ్లను తనిఖీ చేయండి మరియు అనుకూల మోడల్ను వ్రాయడం, టాస్క్ కోసం మోడల్ను చక్కగా తీర్చిదిద్దడం మరియు స్క్రిప్ట్తో మోడల్కు శిక్షణ ఇవ్వడం వంటి మరింత నిర్దిష్టమైన పనులను ఎలా చేయాలో తెలుసుకోండి. 🤗 ట్రాన్స్ఫార్మర్స్ కోర్ కాన్సెప్ట్ల గురించి మరింత తెలుసుకోవడానికి మీకు ఆసక్తి ఉంటే, ఒక కప్పు కాఫీ తాగి, మా కాన్సెప్టువల్ గైడ్లను చూడండి!
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/tr/_toctree.yml b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/tr/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..8401da6e4eb0aedae36913b7e053f8cf842d9d3e
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/tr/_toctree.yml
@@ -0,0 +1,4 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers
+ title: Get started
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/tr/index.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/tr/index.md
new file mode 100644
index 0000000000000000000000000000000000000000..1b2c665e169d808e778852d5fb4292739ed43b6f
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/tr/index.md
@@ -0,0 +1,295 @@
+
+
+# 🤗 Transformers
+
+[PyTorch](https://pytorch.org/), [TensorFlow](https://www.tensorflow.org/) ve [JAX](https://jax.readthedocs.io/en/latest/) için son teknoloji makine öğrenimi.
+
+🤗 Transformers, güncel önceden eğitilmiş (pretrained) modelleri indirmenizi ve eğitmenizi kolaylaştıran API'ler ve araçlar sunar. Önceden eğitilmiş modeller kullanarak, hesaplama maliyetlerinizi ve karbon ayak izinizi azaltabilir, ve sıfırdan bir modeli eğitmek için gereken zaman ve kaynaklardan tasarruf edebilirsiniz. Bu modeller farklı modalitelerde ortak görevleri destekler. Örneğin:
+
+📝 **Doğal Dil İşleme**: metin sınıflandırma, adlandırılmış varlık tanıma, soru cevaplama, dil modelleme, özetleme, çeviri, çoktan seçmeli ve metin oluşturma.
+🖼️ **Bilgisayarlı Görü**: görüntü sınıflandırma, nesne tespiti ve bölümleme (segmentation).
+🗣️ **Ses**: otomatik konuşma tanıma ve ses sınıflandırma.
+🐙 **Çoklu Model**: tablo soru cevaplama, optik karakter tanıma, taranmış belgelerden bilgi çıkarma, video sınıflandırma ve görsel soru cevaplama.
+
+🤗 Transformers, PyTorch, TensorFlow ve JAX arasında çerçeve (framework) uyumluluğu sağlar. Bu, bir modelin yaşam döngüsünün her aşamasında farklı bir çerçeve kullanma esnekliği sunar; bir çerçevede üç satır kodla bir modeli eğitebilir ve başka bir çerçevede tahminleme için kullanabilirsiniz. Modeller ayrıca üretim ortamlarında kullanılmak üzere ONNX ve TorchScript gibi bir formata aktarılabilir.
+
+Büyüyen topluluğa [Hub](https://huggingface.co/models), [Forum](https://discuss.huggingface.co/) veya [Discord](https://discord.com/invite/JfAtkvEtRb) üzerinden katılabilirsiniz!
+
+## Hugging Face ekibinden özel destek arıyorsanız
+
+
+
+
+
+## İçindekiler
+
+Dokümantasyon, beş bölüme ayrılmıştır:
+
+- **BAŞLARKEN**, kütüphanenin hızlı bir turunu ve çalışmaya başlamak için kurulum talimatlarını sağlar.
+- **ÖĞRETİCİLER**, başlangıç yapmak için harika bir yerdir. Bu bölüm, kütüphane kullanmaya başlamak için ihtiyacınız olan temel becerileri kazanmanıza yardımcı olacaktır.
+- **NASIL YAPILIR KILAVUZLARI**, önceden eğitilmiş bir modele dil modellemesi için ince ayar (fine-tuning) yapmak veya özel bir model yazmak, ve paylaşmak gibi belirli bir hedefe nasıl ulaşılacağını gösterir.
+- **KAVRAMSAL REHBERLER**, modellerin, görevlerin ve 🤗 Transformers tasarım felsefesinin temel kavramları ve fikirleri hakkında daha fazla tartışma ve açıklama sunar.
+- **API** tüm sınıfları (class) ve fonksiyonları (functions) açıklar:
+
+ - **ANA SINIFLAR**, yapılandırma, model, tokenizer ve pipeline gibi en önemli sınıfları (classes) ayrıntılandırır.
+ - **MODELLER**, kütüphanede kullanılan her modelle ilgili sınıfları ve fonksiyonları detaylı olarak inceler.
+ - **DAHİLİ YARDIMCILAR**, kullanılan yardımcı sınıfları ve fonksiyonları detaylı olarak inceler.
+
+## Desteklenen Modeller ve Çerçeveler
+
+Aşağıdaki tablo, her bir model için kütüphanede yer alan mevcut desteği temsil etmektedir. Her bir model için bir Python tokenizer'ına ("slow" olarak adlandırılır) sahip olup olmadıkları, 🤗 Tokenizers kütüphanesi tarafından desteklenen hızlı bir tokenizer'a sahip olup olmadıkları, Jax (Flax aracılığıyla), PyTorch ve/veya TensorFlow'da destek olup olmadıklarını göstermektedir.
+
+
+
+| Model | PyTorch support | TensorFlow support | Flax Support |
+|:------------------------------------------------------------------------:|:---------------:|:------------------:|:------------:|
+| [ALBERT](model_doc/albert) | ✅ | ✅ | ✅ |
+| [ALIGN](model_doc/align) | ✅ | ❌ | ❌ |
+| [AltCLIP](model_doc/altclip) | ✅ | ❌ | ❌ |
+| [Audio Spectrogram Transformer](model_doc/audio-spectrogram-transformer) | ✅ | ❌ | ❌ |
+| [Autoformer](model_doc/autoformer) | ✅ | ❌ | ❌ |
+| [Bark](model_doc/bark) | ✅ | ❌ | ❌ |
+| [BART](model_doc/bart) | ✅ | ✅ | ✅ |
+| [BARThez](model_doc/barthez) | ✅ | ✅ | ✅ |
+| [BARTpho](model_doc/bartpho) | ✅ | ✅ | ✅ |
+| [BEiT](model_doc/beit) | ✅ | ❌ | ✅ |
+| [BERT](model_doc/bert) | ✅ | ✅ | ✅ |
+| [Bert Generation](model_doc/bert-generation) | ✅ | ❌ | ❌ |
+| [BertJapanese](model_doc/bert-japanese) | ✅ | ✅ | ✅ |
+| [BERTweet](model_doc/bertweet) | ✅ | ✅ | ✅ |
+| [BigBird](model_doc/big_bird) | ✅ | ❌ | ✅ |
+| [BigBird-Pegasus](model_doc/bigbird_pegasus) | ✅ | ❌ | ❌ |
+| [BioGpt](model_doc/biogpt) | ✅ | ❌ | ❌ |
+| [BiT](model_doc/bit) | ✅ | ❌ | ❌ |
+| [Blenderbot](model_doc/blenderbot) | ✅ | ✅ | ✅ |
+| [BlenderbotSmall](model_doc/blenderbot-small) | ✅ | ✅ | ✅ |
+| [BLIP](model_doc/blip) | ✅ | ✅ | ❌ |
+| [BLIP-2](model_doc/blip-2) | ✅ | ❌ | ❌ |
+| [BLOOM](model_doc/bloom) | ✅ | ❌ | ✅ |
+| [BORT](model_doc/bort) | ✅ | ✅ | ✅ |
+| [BridgeTower](model_doc/bridgetower) | ✅ | ❌ | ❌ |
+| [BROS](model_doc/bros) | ✅ | ❌ | ❌ |
+| [ByT5](model_doc/byt5) | ✅ | ✅ | ✅ |
+| [CamemBERT](model_doc/camembert) | ✅ | ✅ | ❌ |
+| [CANINE](model_doc/canine) | ✅ | ❌ | ❌ |
+| [Chinese-CLIP](model_doc/chinese_clip) | ✅ | ❌ | ❌ |
+| [CLAP](model_doc/clap) | ✅ | ❌ | ❌ |
+| [CLIP](model_doc/clip) | ✅ | ✅ | ✅ |
+| [CLIPSeg](model_doc/clipseg) | ✅ | ❌ | ❌ |
+| [CodeGen](model_doc/codegen) | ✅ | ❌ | ❌ |
+| [CodeLlama](model_doc/code_llama) | ✅ | ❌ | ❌ |
+| [Conditional DETR](model_doc/conditional_detr) | ✅ | ❌ | ❌ |
+| [ConvBERT](model_doc/convbert) | ✅ | ✅ | ❌ |
+| [ConvNeXT](model_doc/convnext) | ✅ | ✅ | ❌ |
+| [ConvNeXTV2](model_doc/convnextv2) | ✅ | ❌ | ❌ |
+| [CPM](model_doc/cpm) | ✅ | ✅ | ✅ |
+| [CPM-Ant](model_doc/cpmant) | ✅ | ❌ | ❌ |
+| [CTRL](model_doc/ctrl) | ✅ | ✅ | ❌ |
+| [CvT](model_doc/cvt) | ✅ | ✅ | ❌ |
+| [Data2VecAudio](model_doc/data2vec) | ✅ | ❌ | ❌ |
+| [Data2VecText](model_doc/data2vec) | ✅ | ❌ | ❌ |
+| [Data2VecVision](model_doc/data2vec) | ✅ | ✅ | ❌ |
+| [DeBERTa](model_doc/deberta) | ✅ | ✅ | ❌ |
+| [DeBERTa-v2](model_doc/deberta-v2) | ✅ | ✅ | ❌ |
+| [Decision Transformer](model_doc/decision_transformer) | ✅ | ❌ | ❌ |
+| [Deformable DETR](model_doc/deformable_detr) | ✅ | ❌ | ❌ |
+| [DeiT](model_doc/deit) | ✅ | ✅ | ❌ |
+| [DePlot](model_doc/deplot) | ✅ | ❌ | ❌ |
+| [DETA](model_doc/deta) | ✅ | ❌ | ❌ |
+| [DETR](model_doc/detr) | ✅ | ❌ | ❌ |
+| [DialoGPT](model_doc/dialogpt) | ✅ | ✅ | ✅ |
+| [DiNAT](model_doc/dinat) | ✅ | ❌ | ❌ |
+| [DINOv2](model_doc/dinov2) | ✅ | ❌ | ❌ |
+| [DistilBERT](model_doc/distilbert) | ✅ | ✅ | ✅ |
+| [DiT](model_doc/dit) | ✅ | ❌ | ✅ |
+| [DonutSwin](model_doc/donut) | ✅ | ❌ | ❌ |
+| [DPR](model_doc/dpr) | ✅ | ✅ | ❌ |
+| [DPT](model_doc/dpt) | ✅ | ❌ | ❌ |
+| [EfficientFormer](model_doc/efficientformer) | ✅ | ✅ | ❌ |
+| [EfficientNet](model_doc/efficientnet) | ✅ | ❌ | ❌ |
+| [ELECTRA](model_doc/electra) | ✅ | ✅ | ✅ |
+| [EnCodec](model_doc/encodec) | ✅ | ❌ | ❌ |
+| [Encoder decoder](model_doc/encoder-decoder) | ✅ | ✅ | ✅ |
+| [ERNIE](model_doc/ernie) | ✅ | ❌ | ❌ |
+| [ErnieM](model_doc/ernie_m) | ✅ | ❌ | ❌ |
+| [ESM](model_doc/esm) | ✅ | ✅ | ❌ |
+| [FairSeq Machine-Translation](model_doc/fsmt) | ✅ | ❌ | ❌ |
+| [Falcon](model_doc/falcon) | ✅ | ❌ | ❌ |
+| [FLAN-T5](model_doc/flan-t5) | ✅ | ✅ | ✅ |
+| [FLAN-UL2](model_doc/flan-ul2) | ✅ | ✅ | ✅ |
+| [FlauBERT](model_doc/flaubert) | ✅ | ✅ | ❌ |
+| [FLAVA](model_doc/flava) | ✅ | ❌ | ❌ |
+| [FNet](model_doc/fnet) | ✅ | ❌ | ❌ |
+| [FocalNet](model_doc/focalnet) | ✅ | ❌ | ❌ |
+| [Funnel Transformer](model_doc/funnel) | ✅ | ✅ | ❌ |
+| [Fuyu](model_doc/fuyu) | ✅ | ❌ | ❌ |
+| [GIT](model_doc/git) | ✅ | ❌ | ❌ |
+| [GLPN](model_doc/glpn) | ✅ | ❌ | ❌ |
+| [GPT Neo](model_doc/gpt_neo) | ✅ | ❌ | ✅ |
+| [GPT NeoX](model_doc/gpt_neox) | ✅ | ❌ | ❌ |
+| [GPT NeoX Japanese](model_doc/gpt_neox_japanese) | ✅ | ❌ | ❌ |
+| [GPT-J](model_doc/gptj) | ✅ | ✅ | ✅ |
+| [GPT-Sw3](model_doc/gpt-sw3) | ✅ | ✅ | ✅ |
+| [GPTBigCode](model_doc/gpt_bigcode) | ✅ | ❌ | ❌ |
+| [GPTSAN-japanese](model_doc/gptsan-japanese) | ✅ | ❌ | ❌ |
+| [Graphormer](model_doc/graphormer) | ✅ | ❌ | ❌ |
+| [GroupViT](model_doc/groupvit) | ✅ | ✅ | ❌ |
+| [HerBERT](model_doc/herbert) | ✅ | ✅ | ✅ |
+| [Hubert](model_doc/hubert) | ✅ | ✅ | ❌ |
+| [I-BERT](model_doc/ibert) | ✅ | ❌ | ❌ |
+| [IDEFICS](model_doc/idefics) | ✅ | ❌ | ❌ |
+| [ImageGPT](model_doc/imagegpt) | ✅ | ❌ | ❌ |
+| [Informer](model_doc/informer) | ✅ | ❌ | ❌ |
+| [InstructBLIP](model_doc/instructblip) | ✅ | ❌ | ❌ |
+| [Jukebox](model_doc/jukebox) | ✅ | ❌ | ❌ |
+| [LayoutLM](model_doc/layoutlm) | ✅ | ✅ | ❌ |
+| [LayoutLMv2](model_doc/layoutlmv2) | ✅ | ❌ | ❌ |
+| [LayoutLMv3](model_doc/layoutlmv3) | ✅ | ✅ | ❌ |
+| [LayoutXLM](model_doc/layoutxlm) | ✅ | ❌ | ❌ |
+| [LED](model_doc/led) | ✅ | ✅ | ❌ |
+| [LeViT](model_doc/levit) | ✅ | ❌ | ❌ |
+| [LiLT](model_doc/lilt) | ✅ | ❌ | ❌ |
+| [LLaMA](model_doc/llama) | ✅ | ❌ | ❌ |
+| [Llama2](model_doc/llama2) | ✅ | ❌ | ❌ |
+| [Longformer](model_doc/longformer) | ✅ | ✅ | ❌ |
+| [LongT5](model_doc/longt5) | ✅ | ❌ | ✅ |
+| [LUKE](model_doc/luke) | ✅ | ❌ | ❌ |
+| [LXMERT](model_doc/lxmert) | ✅ | ✅ | ❌ |
+| [M-CTC-T](model_doc/mctct) | ✅ | ❌ | ❌ |
+| [M2M100](model_doc/m2m_100) | ✅ | ❌ | ❌ |
+| [Marian](model_doc/marian) | ✅ | ✅ | ✅ |
+| [MarkupLM](model_doc/markuplm) | ✅ | ❌ | ❌ |
+| [Mask2Former](model_doc/mask2former) | ✅ | ❌ | ❌ |
+| [MaskFormer](model_doc/maskformer) | ✅ | ❌ | ❌ |
+| [MatCha](model_doc/matcha) | ✅ | ❌ | ❌ |
+| [mBART](model_doc/mbart) | ✅ | ✅ | ✅ |
+| [mBART-50](model_doc/mbart50) | ✅ | ✅ | ✅ |
+| [MEGA](model_doc/mega) | ✅ | ❌ | ❌ |
+| [Megatron-BERT](model_doc/megatron-bert) | ✅ | ❌ | ❌ |
+| [Megatron-GPT2](model_doc/megatron_gpt2) | ✅ | ✅ | ✅ |
+| [MGP-STR](model_doc/mgp-str) | ✅ | ❌ | ❌ |
+| [Mistral](model_doc/mistral) | ✅ | ❌ | ❌ |
+| [mLUKE](model_doc/mluke) | ✅ | ❌ | ❌ |
+| [MMS](model_doc/mms) | ✅ | ✅ | ✅ |
+| [MobileBERT](model_doc/mobilebert) | ✅ | ✅ | ❌ |
+| [MobileNetV1](model_doc/mobilenet_v1) | ✅ | ❌ | ❌ |
+| [MobileNetV2](model_doc/mobilenet_v2) | ✅ | ❌ | ❌ |
+| [MobileViT](model_doc/mobilevit) | ✅ | ✅ | ❌ |
+| [MobileViTV2](model_doc/mobilevitv2) | ✅ | ❌ | ❌ |
+| [MPNet](model_doc/mpnet) | ✅ | ✅ | ❌ |
+| [MPT](model_doc/mpt) | ✅ | ❌ | ❌ |
+| [MRA](model_doc/mra) | ✅ | ❌ | ❌ |
+| [MT5](model_doc/mt5) | ✅ | ✅ | ✅ |
+| [MusicGen](model_doc/musicgen) | ✅ | ❌ | ❌ |
+| [MVP](model_doc/mvp) | ✅ | ❌ | ❌ |
+| [NAT](model_doc/nat) | ✅ | ❌ | ❌ |
+| [Nezha](model_doc/nezha) | ✅ | ❌ | ❌ |
+| [NLLB](model_doc/nllb) | ✅ | ❌ | ❌ |
+| [NLLB-MOE](model_doc/nllb-moe) | ✅ | ❌ | ❌ |
+| [Nougat](model_doc/nougat) | ✅ | ✅ | ✅ |
+| [Nyströmformer](model_doc/nystromformer) | ✅ | ❌ | ❌ |
+| [OneFormer](model_doc/oneformer) | ✅ | ❌ | ❌ |
+| [OpenAI GPT](model_doc/openai-gpt) | ✅ | ✅ | ❌ |
+| [OpenAI GPT-2](model_doc/gpt2) | ✅ | ✅ | ✅ |
+| [OpenLlama](model_doc/open-llama) | ✅ | ❌ | ❌ |
+| [OPT](model_doc/opt) | ✅ | ✅ | ✅ |
+| [OWL-ViT](model_doc/owlvit) | ✅ | ❌ | ❌ |
+| [OWLv2](model_doc/owlv2) | ✅ | ❌ | ❌ |
+| [Pegasus](model_doc/pegasus) | ✅ | ✅ | ✅ |
+| [PEGASUS-X](model_doc/pegasus_x) | ✅ | ❌ | ❌ |
+| [Perceiver](model_doc/perceiver) | ✅ | ❌ | ❌ |
+| [Persimmon](model_doc/persimmon) | ✅ | ❌ | ❌ |
+| [PhoBERT](model_doc/phobert) | ✅ | ✅ | ✅ |
+| [Pix2Struct](model_doc/pix2struct) | ✅ | ❌ | ❌ |
+| [PLBart](model_doc/plbart) | ✅ | ❌ | ❌ |
+| [PoolFormer](model_doc/poolformer) | ✅ | ❌ | ❌ |
+| [Pop2Piano](model_doc/pop2piano) | ✅ | ❌ | ❌ |
+| [ProphetNet](model_doc/prophetnet) | ✅ | ❌ | ❌ |
+| [PVT](model_doc/pvt) | ✅ | ❌ | ❌ |
+| [QDQBert](model_doc/qdqbert) | ✅ | ❌ | ❌ |
+| [RAG](model_doc/rag) | ✅ | ✅ | ❌ |
+| [REALM](model_doc/realm) | ✅ | ❌ | ❌ |
+| [Reformer](model_doc/reformer) | ✅ | ❌ | ❌ |
+| [RegNet](model_doc/regnet) | ✅ | ✅ | ✅ |
+| [RemBERT](model_doc/rembert) | ✅ | ✅ | ❌ |
+| [ResNet](model_doc/resnet) | ✅ | ✅ | ✅ |
+| [RetriBERT](model_doc/retribert) | ✅ | ❌ | ❌ |
+| [RoBERTa](model_doc/roberta) | ✅ | ✅ | ✅ |
+| [RoBERTa-PreLayerNorm](model_doc/roberta-prelayernorm) | ✅ | ✅ | ✅ |
+| [RoCBert](model_doc/roc_bert) | ✅ | ❌ | ❌ |
+| [RoFormer](model_doc/roformer) | ✅ | ✅ | ✅ |
+| [RWKV](model_doc/rwkv) | ✅ | ❌ | ❌ |
+| [SAM](model_doc/sam) | ✅ | ✅ | ❌ |
+| [SeamlessM4T](model_doc/seamless_m4t) | ✅ | ❌ | ❌ |
+| [SegFormer](model_doc/segformer) | ✅ | ✅ | ❌ |
+| [SEW](model_doc/sew) | ✅ | ❌ | ❌ |
+| [SEW-D](model_doc/sew-d) | ✅ | ❌ | ❌ |
+| [Speech Encoder decoder](model_doc/speech-encoder-decoder) | ✅ | ❌ | ✅ |
+| [Speech2Text](model_doc/speech_to_text) | ✅ | ✅ | ❌ |
+| [SpeechT5](model_doc/speecht5) | ✅ | ❌ | ❌ |
+| [Splinter](model_doc/splinter) | ✅ | ❌ | ❌ |
+| [SqueezeBERT](model_doc/squeezebert) | ✅ | ❌ | ❌ |
+| [SwiftFormer](model_doc/swiftformer) | ✅ | ❌ | ❌ |
+| [Swin Transformer](model_doc/swin) | ✅ | ✅ | ❌ |
+| [Swin Transformer V2](model_doc/swinv2) | ✅ | ❌ | ❌ |
+| [Swin2SR](model_doc/swin2sr) | ✅ | ❌ | ❌ |
+| [SwitchTransformers](model_doc/switch_transformers) | ✅ | ❌ | ❌ |
+| [T5](model_doc/t5) | ✅ | ✅ | ✅ |
+| [T5v1.1](model_doc/t5v1.1) | ✅ | ✅ | ✅ |
+| [Table Transformer](model_doc/table-transformer) | ✅ | ❌ | ❌ |
+| [TAPAS](model_doc/tapas) | ✅ | ✅ | ❌ |
+| [TAPEX](model_doc/tapex) | ✅ | ✅ | ✅ |
+| [Time Series Transformer](model_doc/time_series_transformer) | ✅ | ❌ | ❌ |
+| [TimeSformer](model_doc/timesformer) | ✅ | ❌ | ❌ |
+| [Trajectory Transformer](model_doc/trajectory_transformer) | ✅ | ❌ | ❌ |
+| [Transformer-XL](model_doc/transfo-xl) | ✅ | ✅ | ❌ |
+| [TrOCR](model_doc/trocr) | ✅ | ❌ | ❌ |
+| [TVLT](model_doc/tvlt) | ✅ | ❌ | ❌ |
+| [UL2](model_doc/ul2) | ✅ | ✅ | ✅ |
+| [UMT5](model_doc/umt5) | ✅ | ❌ | ❌ |
+| [UniSpeech](model_doc/unispeech) | ✅ | ❌ | ❌ |
+| [UniSpeechSat](model_doc/unispeech-sat) | ✅ | ❌ | ❌ |
+| [UPerNet](model_doc/upernet) | ✅ | ❌ | ❌ |
+| [VAN](model_doc/van) | ✅ | ❌ | ❌ |
+| [VideoMAE](model_doc/videomae) | ✅ | ❌ | ❌ |
+| [ViLT](model_doc/vilt) | ✅ | ❌ | ❌ |
+| [Vision Encoder decoder](model_doc/vision-encoder-decoder) | ✅ | ✅ | ✅ |
+| [VisionTextDualEncoder](model_doc/vision-text-dual-encoder) | ✅ | ✅ | ✅ |
+| [VisualBERT](model_doc/visual_bert) | ✅ | ❌ | ❌ |
+| [ViT](model_doc/vit) | ✅ | ✅ | ✅ |
+| [ViT Hybrid](model_doc/vit_hybrid) | ✅ | ❌ | ❌ |
+| [VitDet](model_doc/vitdet) | ✅ | ❌ | ❌ |
+| [ViTMAE](model_doc/vit_mae) | ✅ | ✅ | ❌ |
+| [ViTMatte](model_doc/vitmatte) | ✅ | ❌ | ❌ |
+| [ViTMSN](model_doc/vit_msn) | ✅ | ❌ | ❌ |
+| [VITS](model_doc/vits) | ✅ | ❌ | ❌ |
+| [ViViT](model_doc/vivit) | ✅ | ❌ | ❌ |
+| [Wav2Vec2](model_doc/wav2vec2) | ✅ | ✅ | ✅ |
+| [Wav2Vec2-Conformer](model_doc/wav2vec2-conformer) | ✅ | ❌ | ❌ |
+| [Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme) | ✅ | ✅ | ✅ |
+| [WavLM](model_doc/wavlm) | ✅ | ❌ | ❌ |
+| [Whisper](model_doc/whisper) | ✅ | ✅ | ✅ |
+| [X-CLIP](model_doc/xclip) | ✅ | ❌ | ❌ |
+| [X-MOD](model_doc/xmod) | ✅ | ❌ | ❌ |
+| [XGLM](model_doc/xglm) | ✅ | ✅ | ✅ |
+| [XLM](model_doc/xlm) | ✅ | ✅ | ❌ |
+| [XLM-ProphetNet](model_doc/xlm-prophetnet) | ✅ | ❌ | ❌ |
+| [XLM-RoBERTa](model_doc/xlm-roberta) | ✅ | ✅ | ✅ |
+| [XLM-RoBERTa-XL](model_doc/xlm-roberta-xl) | ✅ | ❌ | ❌ |
+| [XLM-V](model_doc/xlm-v) | ✅ | ✅ | ✅ |
+| [XLNet](model_doc/xlnet) | ✅ | ✅ | ❌ |
+| [XLS-R](model_doc/xls_r) | ✅ | ✅ | ✅ |
+| [XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2) | ✅ | ✅ | ✅ |
+| [YOLOS](model_doc/yolos) | ✅ | ❌ | ❌ |
+| [YOSO](model_doc/yoso) | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/zh/_toctree.yml b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/zh/_toctree.yml
new file mode 100644
index 0000000000000000000000000000000000000000..a848a6bd6a5b63097189335e709d8d4c09ea7d71
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/zh/_toctree.yml
@@ -0,0 +1,167 @@
+- sections:
+ - local: index
+ title: 🤗 Transformers 简介
+ - local: quicktour
+ title: 快速上手
+ - local: installation
+ title: 安装
+ title: 开始使用
+- sections:
+ - local: pipeline_tutorial
+ title: 使用pipelines进行推理
+ - local: autoclass_tutorial
+ title: 使用AutoClass编写可移植的代码
+ - local: preprocessing
+ title: 预处理数据
+ - local: training
+ title: 微调预训练模型
+ - local: run_scripts
+ title: 通过脚本训练模型
+ - local: accelerate
+ title: 使用🤗Accelerate进行分布式训练
+ - local: peft
+ title: 使用🤗 PEFT加载和训练adapters
+ - local: model_sharing
+ title: 分享您的模型
+ - local: agents
+ title: 智能体和工具
+ - local: agents_advanced
+ title: 智能体,超强版 - 多智能体、外部工具等
+ - local: llm_tutorial
+ title: 使用LLMs进行生成
+ title: 教程
+- sections:
+ - isExpanded: false
+ sections:
+ - local: tasks/asr
+ title: 自动语音识别
+- sections:
+ - local: fast_tokenizers
+ title: 使用 🤗 Tokenizers 中的分词器
+ - local: multilingual
+ title: 使用多语言模型进行推理
+ - local: create_a_model
+ title: 使用特定于模型的 API
+ - local: custom_models
+ title: 共享自定义模型
+ - local: chat_templating
+ title: 聊天模型的模板
+ - local: serialization
+ title: 导出为 ONNX
+ - local: tflite
+ title: 导出为 TFLite
+ - local: torchscript
+ title: 导出为 TorchScript
+ - local: gguf
+ title: 与 GGUF 格式的互操作性
+ - local: tiktoken
+ title: 与 Tiktoken 文件的互操作性
+ - local: community
+ title: 社区资源
+ title: 开发者指南
+- sections:
+ - local: performance
+ title: 综述
+ - sections:
+ - local: fsdp
+ title: 完全分片数据并行
+ - local: perf_train_special
+ title: 在 Apple silicon 芯片上进行 PyTorch 训练
+ - local: perf_infer_gpu_multi
+ title: 多GPU推理
+ - local: perf_train_cpu
+ title: 在CPU上进行高效训练
+ - local: perf_hardware
+ title: 用于训练的定制硬件
+ - local: hpo_train
+ title: 使用Trainer API 进行超参数搜索
+ title: 高效训练技术
+ - local: big_models
+ title: 实例化大模型
+ - local: debugging
+ title: 问题定位及解决
+ - local: tf_xla
+ title: TensorFlow模型的XLA集成
+ - local: perf_torch_compile
+ title: 使用 `torch.compile()` 优化推理
+ title: 性能和可扩展性
+- sections:
+ - local: contributing
+ title: 如何为 🤗 Transformers 做贡献?
+ - local: add_new_pipeline
+ title: 如何将流水线添加到 🤗 Transformers?
+ title: 贡献
+- sections:
+ - local: philosophy
+ title: Transformers的设计理念
+ - local: task_summary
+ title: 🤗Transformers能做什么
+ - local: tokenizer_summary
+ title: 分词器的摘要
+ - local: attention
+ title: 注意力机制
+ - local: bertology
+ title: 基于BERT进行的相关研究
+ title: 概念指南
+- sections:
+ - sections:
+ - local: main_classes/agent
+ title: 智能体和工具
+ - local: main_classes/callback
+ title: Callbacks
+ - local: main_classes/configuration
+ title: Configuration
+ - local: main_classes/data_collator
+ title: Data Collator
+ - local: main_classes/keras_callbacks
+ title: Keras callbacks
+ - local: main_classes/logging
+ title: Logging
+ - local: main_classes/model
+ title: 模型
+ - local: main_classes/text_generation
+ title: 文本生成
+ - local: main_classes/onnx
+ title: ONNX
+ - local: main_classes/optimizer_schedules
+ title: Optimization
+ - local: main_classes/output
+ title: 模型输出
+ - local: main_classes/pipelines
+ title: Pipelines
+ - local: main_classes/processors
+ title: Processors
+ - local: main_classes/quantization
+ title: Quantization
+ - local: main_classes/tokenizer
+ title: Tokenizer
+ - local: main_classes/trainer
+ title: Trainer
+ - local: main_classes/deepspeed
+ title: DeepSpeed集成
+ - local: main_classes/feature_extractor
+ title: Feature Extractor
+ - local: main_classes/image_processor
+ title: Image Processor
+ title: 主要类
+ - sections:
+ - local: internal/modeling_utils
+ title: 自定义层和工具
+ - local: internal/pipelines_utils
+ title: pipelines工具
+ - local: internal/tokenization_utils
+ title: Tokenizers工具
+ - local: internal/trainer_utils
+ title: 训练器工具
+ - local: internal/generation_utils
+ title: 生成工具
+ - local: internal/image_processing_utils
+ title: 图像处理工具
+ - local: internal/audio_utils
+ title: 音频处理工具
+ - local: internal/file_utils
+ title: 通用工具
+ - local: internal/time_series_utils
+ title: 时序数据工具
+ title: 内部辅助工具
+ title: 应用程序接口 (API)
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/zh/accelerate.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/zh/accelerate.md
new file mode 100644
index 0000000000000000000000000000000000000000..12c626199477dd14cfc322f642909132832cf258
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/zh/accelerate.md
@@ -0,0 +1,132 @@
+
+
+# 🤗 加速分布式训练
+
+随着模型变得越来越大,并行性已经成为在有限硬件上训练更大模型和加速训练速度的策略,增加了数个数量级。在Hugging Face,我们创建了[🤗 加速](https://huggingface.co/docs/accelerate)库,以帮助用户在任何类型的分布式设置上轻松训练🤗 Transformers模型,无论是在一台机器上的多个GPU还是在多个机器上的多个GPU。在本教程中,了解如何自定义您的原生PyTorch训练循环,以启用分布式环境中的训练。
+
+## 设置
+
+通过安装🤗 加速开始:
+
+```bash
+pip install accelerate
+```
+
+然后导入并创建[`~accelerate.Accelerator`]对象。[`~accelerate.Accelerator`]将自动检测您的分布式设置类型,并初始化所有必要的训练组件。您不需要显式地将模型放在设备上。
+
+```py
+>>> from accelerate import Accelerator
+
+>>> accelerator = Accelerator()
+```
+
+## 准备加速
+
+下一步是将所有相关的训练对象传递给[`~accelerate.Accelerator.prepare`]方法。这包括您的训练和评估DataLoader、一个模型和一个优化器:
+
+```py
+>>> train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
+... train_dataloader, eval_dataloader, model, optimizer
+... )
+```
+
+## 反向传播
+
+最后一步是用🤗 加速的[`~accelerate.Accelerator.backward`]方法替换训练循环中的典型`loss.backward()`:
+
+```py
+>>> for epoch in range(num_epochs):
+... for batch in train_dataloader:
+... outputs = model(**batch)
+... loss = outputs.loss
+... accelerator.backward(loss)
+
+... optimizer.step()
+... lr_scheduler.step()
+... optimizer.zero_grad()
+... progress_bar.update(1)
+```
+
+如您在下面的代码中所见,您只需要添加四行额外的代码到您的训练循环中即可启用分布式训练!
+
+```diff
++ from accelerate import Accelerator
+ from transformers import AdamW, AutoModelForSequenceClassification, get_scheduler
+
++ accelerator = Accelerator()
+
+ model = AutoModelForSequenceClassification.from_pretrained(checkpoint, num_labels=2)
+ optimizer = AdamW(model.parameters(), lr=3e-5)
+
+- device = torch.device("cuda") if torch.cuda.is_available() else torch.device("cpu")
+- model.to(device)
+
++ train_dataloader, eval_dataloader, model, optimizer = accelerator.prepare(
++ train_dataloader, eval_dataloader, model, optimizer
++ )
+
+ num_epochs = 3
+ num_training_steps = num_epochs * len(train_dataloader)
+ lr_scheduler = get_scheduler(
+ "linear",
+ optimizer=optimizer,
+ num_warmup_steps=0,
+ num_training_steps=num_training_steps
+ )
+
+ progress_bar = tqdm(range(num_training_steps))
+
+ model.train()
+ for epoch in range(num_epochs):
+ for batch in train_dataloader:
+- batch = {k: v.to(device) for k, v in batch.items()}
+ outputs = model(**batch)
+ loss = outputs.loss
+- loss.backward()
++ accelerator.backward(loss)
+
+ optimizer.step()
+ lr_scheduler.step()
+ optimizer.zero_grad()
+ progress_bar.update(1)
+```
+
+## 训练
+
+在添加了相关代码行后,可以在脚本或笔记本(如Colaboratory)中启动训练。
+
+### 用脚本训练
+
+如果您从脚本中运行训练,请运行以下命令以创建和保存配置文件:
+
+```bash
+accelerate config
+```
+
+然后使用以下命令启动训练:
+
+```bash
+accelerate launch train.py
+```
+
+### 用笔记本训练
+
+🤗 加速还可以在笔记本中运行,如果您计划使用Colaboratory的TPU,则可在其中运行。将负责训练的所有代码包装在一个函数中,并将其传递给[`~accelerate.notebook_launcher`]:
+
+```py
+>>> from accelerate import notebook_launcher
+
+>>> notebook_launcher(training_function)
+```
+
+有关🤗 加速及其丰富功能的更多信息,请参阅[文档](https://huggingface.co/docs/accelerate)。
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/zh/add_new_pipeline.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/zh/add_new_pipeline.md
new file mode 100644
index 0000000000000000000000000000000000000000..57fd53636b0a1360f44ecf9af9f94c37d1e84f45
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/zh/add_new_pipeline.md
@@ -0,0 +1,238 @@
+
+
+# 如何创建自定义流水线?
+
+在本指南中,我们将演示如何创建一个自定义流水线并分享到 [Hub](https://hf.co/models),或将其添加到 🤗 Transformers 库中。
+
+首先,你需要决定流水线将能够接受的原始条目。它可以是字符串、原始字节、字典或任何看起来最可能是期望的输入。
+尽量保持输入为纯 Python 语言,因为这样可以更容易地实现兼容性(甚至通过 JSON 在其他语言之间)。
+这些将是流水线 (`preprocess`) 的 `inputs`。
+
+然后定义 `outputs`。与 `inputs` 相同的策略。越简单越好。这些将是 `postprocess` 方法的输出。
+
+首先继承基类 `Pipeline`,其中包含实现 `preprocess`、`_forward`、`postprocess` 和 `_sanitize_parameters` 所需的 4 个方法。
+
+```python
+from transformers import Pipeline
+
+
+class MyPipeline(Pipeline):
+ def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "maybe_arg" in kwargs:
+ preprocess_kwargs["maybe_arg"] = kwargs["maybe_arg"]
+ return preprocess_kwargs, {}, {}
+
+ def preprocess(self, inputs, maybe_arg=2):
+ model_input = Tensor(inputs["input_ids"])
+ return {"model_input": model_input}
+
+ def _forward(self, model_inputs):
+ # model_inputs == {"model_input": model_input}
+ outputs = self.model(**model_inputs)
+ # Maybe {"logits": Tensor(...)}
+ return outputs
+
+ def postprocess(self, model_outputs):
+ best_class = model_outputs["logits"].softmax(-1)
+ return best_class
+```
+
+这种分解的结构旨在为 CPU/GPU 提供相对无缝的支持,同时支持在不同线程上对 CPU 进行预处理/后处理。
+
+`preprocess` 将接受最初定义的输入,并将其转换为可供模型输入的内容。它可能包含更多信息,通常是一个 `Dict`。
+
+`_forward` 是实现细节,不应直接调用。`forward` 是首选的调用方法,因为它包含保障措施,以确保一切都在预期的设备上运作。
+如果任何内容与实际模型相关,它应该属于 `_forward` 方法,其他内容应该在 preprocess/postprocess 中。
+
+`postprocess` 方法将接受 `_forward` 的输出,并将其转换为之前确定的最终输出。
+
+`_sanitize_parameters` 存在是为了允许用户在任何时候传递任何参数,无论是在初始化时 `pipeline(...., maybe_arg=4)`
+还是在调用时 `pipe = pipeline(...); output = pipe(...., maybe_arg=4)`。
+
+`_sanitize_parameters` 的返回值是将直接传递给 `preprocess`、`_forward` 和 `postprocess` 的 3 个关键字参数字典。
+如果调用方没有使用任何额外参数调用,则不要填写任何内容。这样可以保留函数定义中的默认参数,这总是更"自然"的。
+
+在分类任务中,一个经典的例子是在后处理中使用 `top_k` 参数。
+
+```python
+>>> pipe = pipeline("my-new-task")
+>>> pipe("This is a test")
+[{"label": "1-star", "score": 0.8}, {"label": "2-star", "score": 0.1}, {"label": "3-star", "score": 0.05}
+{"label": "4-star", "score": 0.025}, {"label": "5-star", "score": 0.025}]
+
+>>> pipe("This is a test", top_k=2)
+[{"label": "1-star", "score": 0.8}, {"label": "2-star", "score": 0.1}]
+```
+
+为了实现这一点,我们将更新我们的 `postprocess` 方法,将默认参数设置为 `5`,
+并编辑 `_sanitize_parameters` 方法,以允许这个新参数。
+
+```python
+def postprocess(self, model_outputs, top_k=5):
+ best_class = model_outputs["logits"].softmax(-1)
+ # Add logic to handle top_k
+ return best_class
+
+
+def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "maybe_arg" in kwargs:
+ preprocess_kwargs["maybe_arg"] = kwargs["maybe_arg"]
+
+ postprocess_kwargs = {}
+ if "top_k" in kwargs:
+ postprocess_kwargs["top_k"] = kwargs["top_k"]
+ return preprocess_kwargs, {}, postprocess_kwargs
+```
+
+尽量保持简单输入/输出,最好是可 JSON 序列化的,因为这样可以使流水线的使用非常简单,而不需要用户了解新的对象类型。
+通常也相对常见地支持许多不同类型的参数以便使用(例如音频文件,可以是文件名、URL 或纯字节)。
+
+## 将其添加到支持的任务列表中
+
+要将你的 `new-task` 注册到支持的任务列表中,你需要将其添加到 `PIPELINE_REGISTRY` 中:
+
+```python
+from transformers.pipelines import PIPELINE_REGISTRY
+
+PIPELINE_REGISTRY.register_pipeline(
+ "new-task",
+ pipeline_class=MyPipeline,
+ pt_model=AutoModelForSequenceClassification,
+)
+```
+
+如果需要,你可以指定一个默认模型,此时它应该带有一个特定的修订版本(可以是分支名称或提交哈希,这里我们使用了 `"abcdef"`),以及类型:
+
+```python
+PIPELINE_REGISTRY.register_pipeline(
+ "new-task",
+ pipeline_class=MyPipeline,
+ pt_model=AutoModelForSequenceClassification,
+ default={"pt": ("user/awesome_model", "abcdef")},
+ type="text", # current support type: text, audio, image, multimodal
+)
+```
+
+## 在 Hub 上分享你的流水线
+
+要在 Hub 上分享你的自定义流水线,你只需要将 `Pipeline` 子类的自定义代码保存在一个 Python 文件中。
+例如,假设我们想使用一个自定义流水线进行句对分类,如下所示:
+
+```py
+import numpy as np
+
+from transformers import Pipeline
+
+
+def softmax(outputs):
+ maxes = np.max(outputs, axis=-1, keepdims=True)
+ shifted_exp = np.exp(outputs - maxes)
+ return shifted_exp / shifted_exp.sum(axis=-1, keepdims=True)
+
+
+class PairClassificationPipeline(Pipeline):
+ def _sanitize_parameters(self, **kwargs):
+ preprocess_kwargs = {}
+ if "second_text" in kwargs:
+ preprocess_kwargs["second_text"] = kwargs["second_text"]
+ return preprocess_kwargs, {}, {}
+
+ def preprocess(self, text, second_text=None):
+ return self.tokenizer(text, text_pair=second_text, return_tensors=self.framework)
+
+ def _forward(self, model_inputs):
+ return self.model(**model_inputs)
+
+ def postprocess(self, model_outputs):
+ logits = model_outputs.logits[0].numpy()
+ probabilities = softmax(logits)
+
+ best_class = np.argmax(probabilities)
+ label = self.model.config.id2label[best_class]
+ score = probabilities[best_class].item()
+ logits = logits.tolist()
+ return {"label": label, "score": score, "logits": logits}
+```
+
+这个实现与框架无关,适用于 PyTorch 和 TensorFlow 模型。如果我们将其保存在一个名为
+`pair_classification.py` 的文件中,然后我们可以像这样导入并注册它:
+
+```py
+from pair_classification import PairClassificationPipeline
+from transformers.pipelines import PIPELINE_REGISTRY
+from transformers import AutoModelForSequenceClassification, TFAutoModelForSequenceClassification
+
+PIPELINE_REGISTRY.register_pipeline(
+ "pair-classification",
+ pipeline_class=PairClassificationPipeline,
+ pt_model=AutoModelForSequenceClassification,
+ tf_model=TFAutoModelForSequenceClassification,
+)
+```
+
+完成这些步骤后,我们可以将其与预训练模型一起使用。例如,`sgugger/finetuned-bert-mrpc`
+已经在 MRPC 数据集上进行了微调,用于将句子对分类为是释义或不是释义。
+
+```py
+from transformers import pipeline
+
+classifier = pipeline("pair-classification", model="sgugger/finetuned-bert-mrpc")
+```
+
+然后,我们可以通过在 `Repository` 中使用 `save_pretrained` 方法将其分享到 Hub 上:
+
+```py
+from huggingface_hub import Repository
+
+repo = Repository("test-dynamic-pipeline", clone_from="{your_username}/test-dynamic-pipeline")
+classifier.save_pretrained("test-dynamic-pipeline")
+repo.push_to_hub()
+```
+
+这将会复制包含你定义的 `PairClassificationPipeline` 的文件到文件夹 `"test-dynamic-pipeline"` 中,
+同时保存流水线的模型和分词器,然后将所有内容推送到仓库 `{your_username}/test-dynamic-pipeline` 中。
+之后,只要提供选项 `trust_remote_code=True`,任何人都可以使用它:
+
+```py
+from transformers import pipeline
+
+classifier = pipeline(model="{your_username}/test-dynamic-pipeline", trust_remote_code=True)
+```
+
+## 将流水线添加到 🤗 Transformers
+
+如果你想将你的流水线贡献给 🤗 Transformers,你需要在 `pipelines` 子模块中添加一个新模块,
+其中包含你的流水线的代码,然后将其添加到 `pipelines/__init__.py` 中定义的任务列表中。
+
+然后,你需要添加测试。创建一个新文件 `tests/test_pipelines_MY_PIPELINE.py`,其中包含其他测试的示例。
+
+`run_pipeline_test` 函数将非常通用,并在每种可能的架构上运行小型随机模型,如 `model_mapping` 和 `tf_model_mapping` 所定义。
+
+这对于测试未来的兼容性非常重要,这意味着如果有人为 `XXXForQuestionAnswering` 添加了一个新模型,
+流水线测试将尝试在其上运行。由于模型是随机的,所以不可能检查实际值,这就是为什么有一个帮助函数 `ANY`,它只是尝试匹配流水线的输出类型。
+
+你还 **需要** 实现 2(最好是 4)个测试。
+
+- `test_small_model_pt`:为这个流水线定义一个小型模型(结果是否合理并不重要),并测试流水线的输出。
+ 结果应该与 `test_small_model_tf` 的结果相同。
+- `test_small_model_tf`:为这个流水线定义一个小型模型(结果是否合理并不重要),并测试流水线的输出。
+ 结果应该与 `test_small_model_pt` 的结果相同。
+- `test_large_model_pt`(可选):在一个真实的流水线上测试流水线,结果应该是有意义的。
+ 这些测试速度较慢,应该被如此标记。这里的目标是展示流水线,并确保在未来的发布中没有漂移。
+- `test_large_model_tf`(可选):在一个真实的流水线上测试流水线,结果应该是有意义的。
+ 这些测试速度较慢,应该被如此标记。这里的目标是展示流水线,并确保在未来的发布中没有漂移。
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/zh/agents.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/zh/agents.md
new file mode 100644
index 0000000000000000000000000000000000000000..00fa74e65450259503cf5a0ccc0786b4449d7b45
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/zh/agents.md
@@ -0,0 +1,427 @@
+
+# 智能体和工具
+
+[[在colab里打开]]
+
+### 什么是智能体 (Agent)?
+
+大型语言模型(LLM)经过 [因果语言建模训练](./tasks/language_modeling) 可以应对各种任务,但在一些基本任务(如逻辑推理、计算和搜索)上常常表现不佳。当它们被用在自己不擅长的领域时,往往无法生成我们期望的答案。
+
+为了解决这个问题,可以创建**智能体**.
+
+智能体是一个系统,它使用 LLM 作为引擎,并且能够访问称为**工具**的功能。
+
+这些**工具**是执行任务的函数,包含所有必要的描述信息,帮助智能体正确使用它们。
+
+智能体可以被编程为:
+- 一次性设计一系列工具并同时执行它们,像 [`CodeAgent`]
+- 一次执行一个工具,并等待每个工具的结果后再启动下一个,像 [`ReactJsonAgent`]
+
+### 智能体类型
+
+#### 代码智能体
+
+此智能体包含一个规划步骤,然后生成 Python 代码一次性执行所有任务。它原生支持处理不同输入和输出类型,因此推荐用于多模态任务。
+
+#### 推理智能体
+
+这是解决推理任务的首选代理,因为 ReAct 框架 ([Yao et al., 2022](https://huggingface.co/papers/2210.03629)) 使其在基于之前观察进行推理时非常高效。
+
+我们实现了两种版本的 ReactJsonAgent:
+- [`ReactJsonAgent`] 将工具调用作为 JSON 格式输出。
+- [`ReactCodeAgent`] 是 ReactJsonAgent 的一种新型,生成工具调用的代码块,对于具备强大编程能力的 LLM 非常适用。
+
+> [TIP]
+> 阅读 [Open-source LLMs as LangChain Agents](https://huggingface.co/blog/open-source-llms-as-agents) 博文,了解更多关于推理智能体的信息。
+
+
+
+
+
+
+
+
+以下是一个推理代码智能体如何处理以下问题的示例:
+
+```py3
+>>> agent.run(
+... "How many more blocks (also denoted as layers) in BERT base encoder than the encoder from the architecture proposed in Attention is All You Need?",
+... )
+=====New task=====
+How many more blocks (also denoted as layers) in BERT base encoder than the encoder from the architecture proposed in Attention is All You Need?
+====Agent is executing the code below:
+bert_blocks = search(query="number of blocks in BERT base encoder")
+print("BERT blocks:", bert_blocks)
+====
+Print outputs:
+BERT blocks: twelve encoder blocks
+
+====Agent is executing the code below:
+attention_layer = search(query="number of layers in Attention is All You Need")
+print("Attention layers:", attention_layer)
+====
+Print outputs:
+Attention layers: Encoder: The encoder is composed of a stack of N = 6 identical layers. Each layer has two sub-layers. The first is a multi-head self-attention mechanism, and the second is a simple, position- 2 Page 3 Figure 1: The Transformer - model architecture.
+
+====Agent is executing the code below:
+bert_blocks = 12
+attention_layers = 6
+diff = bert_blocks - attention_layers
+print("Difference in blocks:", diff)
+final_answer(diff)
+====
+
+Print outputs:
+Difference in blocks: 6
+
+Final answer: 6
+```
+
+### 如何构建智能体?
+
+要初始化一个智能体,您需要以下参数:
+
+- **一个 LLM** 来驱动智能体——智能体本身并不是 LLM,而是一个使用 LLM 作为引擎的程序。
+- **一个系统提示**:告诉 LLM 引擎应该如何生成输出。
+- **一个工具箱**,智能体可以从中选择工具执行。
+- **一个解析器**,从 LLM 输出中提取出哪些工具需要调用,以及使用哪些参数。
+
+在智能体系统初始化时,工具属性将生成工具描述,并嵌入到智能体的系统提示中,告知智能体可以使用哪些工具,并且为什么使用它们。
+
+**安装依赖**
+
+首先,您需要安装**智能体**所需的额外依赖:
+
+```bash
+pip install transformers[agents]
+```
+**创建LLM引擎**
+
+定义一个 `llm_engine` 方法,该方法接受一系列[消息](./chat_templating)并返回文本。该 `callable` 还需要接受一个 `stop` 参数,用于指示何时停止生成输出。
+
+```python
+from huggingface_hub import login, InferenceClient
+
+login("")
+
+client = InferenceClient(model="meta-llama/Meta-Llama-3-70B-Instruct")
+
+def llm_engine(messages, stop_sequences=["Task"]) -> str:
+ response = client.chat_completion(messages, stop=stop_sequences, max_tokens=1000)
+ answer = response.choices[0].message.content
+ return answer
+```
+
+您可以使用任何符合以下要求的 `llm_engine` 方法:
+1. [输入格式](./chat_templating)为 (`List[Dict[str, str]]`),并且返回一个字符串。
+2. 它在 `stop_sequences` 参数传递的序列处停止生成输出。
+
+此外,`llm_engine` 还可以接受一个 `grammar` 参数。如果在智能体初始化时指定了 `grammar`,则该参数将传递给 `llm_engine` 的调用,以允许[受限生成](https://huggingface.co/docs/text-generation-inference/conceptual/guidance),以强制生成格式正确的智能体输出。
+
+您还需要一个 `tools` 参数,它接受一个 `Tools` 列表 —— 可以是空列表。您也可以通过定义可选参数 `add_base_tools=True` 来将默认工具箱添加到工具列表中。
+
+现在,您可以创建一个智能体,例如 [`CodeAgent`],并运行它。您还可以创建一个 [`TransformersEngine`],使用 `transformers` 在本地机器上运行预初始化的推理管道。 为了方便起见,由于智能体行为通常需要更强大的模型,例如 `Llama-3.1-70B-Instruct`,它们目前较难在本地运行,我们还提供了 [`HfApiEngine`] 类,它在底层初始化了一个 `huggingface_hub.InferenceClient`。
+
+```python
+from transformers import CodeAgent, HfApiEngine
+
+llm_engine = HfApiEngine(model="meta-llama/Meta-Llama-3-70B-Instruct")
+agent = CodeAgent(tools=[], llm_engine=llm_engine, add_base_tools=True)
+
+agent.run(
+ "Could you translate this sentence from French, say it out loud and return the audio.",
+ sentence="Où est la boulangerie la plus proche?",
+)
+```
+
+当你急需某个东西时这将会很有用!
+您甚至可以将 `llm_engine` 参数留空,默认情况下会创建一个 [`HfApiEngine`]。
+
+```python
+from transformers import CodeAgent
+
+agent = CodeAgent(tools=[], add_base_tools=True)
+
+agent.run(
+ "Could you translate this sentence from French, say it out loud and give me the audio.",
+ sentence="Où est la boulangerie la plus proche?",
+)
+```
+
+请注意,我们使用了额外的 `sentence` 参数:您可以将文本作为附加参数传递给模型。
+
+您还可以使用这个来指定本地或远程文件的路径供模型使用:
+
+```py
+from transformers import ReactCodeAgent
+
+agent = ReactCodeAgent(tools=[], llm_engine=llm_engine, add_base_tools=True)
+
+agent.run("Why does Mike not know many people in New York?", audio="https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/recording.mp3")
+```
+
+系统提示和输出解析器会自动定义,但您可以通过调用智能体的 `system_prompt_template` 来轻松查看它们。
+
+```python
+print(agent.system_prompt_template)
+```
+
+尽可能清楚地解释您要执行的任务非常重要。 每次 [`~Agent.run`] 操作都是独立的,并且由于智能体是由 LLM 驱动的,提示中的细微变化可能会导致完全不同的结果。
+您还可以连续运行多个任务,每次都会重新初始化智能体的 `agent.task` 和 `agent.logs` 属性。
+
+
+#### 代码执行
+
+Python 解释器在一组输入和工具上执行代码。 这应该是安全的,因为只能调用您提供的工具(特别是 Hugging Face 的工具)和 print 函数,因此您已经限制了可以执行的操作。
+
+Python 解释器默认不允许导入不在安全列表中的模块,因此大多数明显的攻击问题应该不成问题。 您仍然可以通过在 [`ReactCodeAgent`] 或 [`CodeAgent`] 初始化时通过 `additional_authorized_imports` 参数传递一个授权的模块列表来授权额外的导入:
+
+```py
+>>> from transformers import ReactCodeAgent
+
+>>> agent = ReactCodeAgent(tools=[], additional_authorized_imports=['requests', 'bs4'])
+>>> agent.run("Could you get me the title of the page at url 'https://huggingface.co/blog'?")
+
+(...)
+'Hugging Face – Blog'
+```
+
+如果有任何代码尝试执行非法操作,或者生成的代码出现常规 Python 错误,执行将停止。
+
+> [!WARNING]
+> 在使用大语言模型(LLM)生成代码时,生成的代码会被执行,避免导入或使用任何不安全的库或模块。
+
+### 系统提示
+
+智能体,或者说驱动智能体的 LLM,根据系统提示生成输出。系统提示可以定制并根据目标任务进行调整。例如,检查 [`ReactCodeAgent`] 的系统提示(以下版本经过简化)。
+
+```text
+You will be given a task to solve as best you can.
+You have access to the following tools:
+<>
+
+To solve the task, you must plan forward to proceed in a series of steps, in a cycle of 'Thought:', 'Code:', and 'Observation:' sequences.
+
+At each step, in the 'Thought:' sequence, you should first explain your reasoning towards solving the task, then the tools that you want to use.
+Then in the 'Code:' sequence, you should write the code in simple Python. The code sequence must end with '/End code' sequence.
+During each intermediate step, you can use 'print()' to save whatever important information you will then need.
+These print outputs will then be available in the 'Observation:' field, for using this information as input for the next step.
+
+In the end you have to return a final answer using the `final_answer` tool.
+
+Here are a few examples using notional tools:
+---
+{examples}
+
+Above example were using notional tools that might not exist for you. You only have acces to those tools:
+<>
+You also can perform computations in the python code you generate.
+
+Always provide a 'Thought:' and a 'Code:\n```py' sequence ending with '```' sequence. You MUST provide at least the 'Code:' sequence to move forward.
+
+Remember to not perform too many operations in a single code block! You should split the task into intermediate code blocks.
+Print results at the end of each step to save the intermediate results. Then use final_answer() to return the final result.
+
+Remember to make sure that variables you use are all defined.
+
+Now Begin!
+```
+
+系统提示包括:
+- 解释智能体应该如何工作以及工具的**介绍**。
+- 所有工具的描述由 `<>` 标记在运行时动态替换,这样智能体就知道可以使用哪些工具及其用途。
+ - 工具的描述来自工具的属性,`name`、`description`、`inputs` 和 `output_type`,以及一个简单的 `jinja2` 模板,您可以根据需要进行调整。
+- 期望的输出格式。
+
+您可以通过向 `system_prompt` 参数传递自定义提示来最大程度地提高灵活性,从而覆盖整个系统提示模板。
+
+```python
+from transformers import ReactJsonAgent
+from transformers.agents import PythonInterpreterTool
+
+agent = ReactJsonAgent(tools=[PythonInterpreterTool()], system_prompt="{your_custom_prompt}")
+```
+
+> [WARNING]
+> 必须在`template`中定义 `<>` 这个变量,以便智能体能够正确地识别并使用可用的工具
+
+
+### 检查智能体的运行
+
+以下是检查运行后发生了什么的一些有用属性:
+- `agent.logs` 存储了智能体的详细日志。每一步的所有内容都会存储在一个字典中,然后附加到 `agent.logs`。
+- 运行 `agent.write_inner_memory_from_logs()` 会从日志中创建智能体的内存,以便 LLM 查看,作为一系列聊天消息。此方法会遍历日志的每个步骤,只保存其感兴趣的消息:例如,它会单独保存系统提示和任务,然后为每个步骤保存 LLM 输出的消息,以及工具调用输出的消息。如果您想要更高层次的查看发生了什么,可以使用此方法 —— 但并不是每个日志都会被此方法转录。
+
+## 工具
+
+工具是智能体使用的基本功能。
+
+例如,您可以检查 [`PythonInterpreterTool`]:它有一个名称、描述、输入描述、输出类型和 `__call__` 方法来执行该操作。
+
+当智能体初始化时,工具属性会用来生成工具描述,然后将其嵌入到智能体的系统提示中,这让智能体知道可以使用哪些工具以及为什么使用它们。
+
+### 默认工具箱
+
+Transformers 提供了一个默认工具箱,用于增强智能体,您可以在初始化时通过 `add_base_tools=True` 参数将其添加到智能体中:
+
+- **文档问答**:给定一个文档(如图像格式的 PDF),回答关于该文档的问题([Donut](./model_doc/donut))
+- **图像问答**:给定一张图片,回答关于该图像的问题([VILT](./model_doc/vilt))
+- **语音转文本**:给定一个人讲述的音频录音,将其转录为文本(Whisper)
+- **文本转语音**:将文本转换为语音([SpeechT5](./model_doc/speecht5))
+- **翻译**:将给定的句子从源语言翻译为目标语言
+- **DuckDuckGo 搜索**:使用 `DuckDuckGo` 浏览器进行网络搜索
+- **Python 代码解释器**:在安全环境中运行 LLM 生成的 Python 代码。只有在初始化 [`ReactJsonAgent`] 时将 `add_base_tools=True` 时,代码智能体才会添加此工具,因为基于代码的智能体已经能够原生执行 Python 代码
+
+
+您可以通过调用 [`load_tool`] 函数来手动使用某个工具并执行任务。
+
+
+```python
+from transformers import load_tool
+
+tool = load_tool("text-to-speech")
+audio = tool("This is a text to speech tool")
+```
+
+
+### 创建新工具
+
+您可以为 `Hugging Face` 默认工具无法涵盖的用例创建自己的工具。
+例如,假设我们要创建一个返回在 `Hugging Face Hub` 上某个任务中下载次数最多的模型的工具。
+
+您将从以下代码开始:
+
+```python
+from huggingface_hub import list_models
+
+task = "text-classification"
+
+model = next(iter(list_models(filter=task, sort="downloads", direction=-1)))
+print(model.id)
+```
+
+这段代码可以很快转换为工具,只需将其包装成一个函数,并添加 `tool` 装饰器:
+
+
+```py
+from transformers import tool
+
+@tool
+def model_download_tool(task: str) -> str:
+ """
+ This is a tool that returns the most downloaded model of a given task on the Hugging Face Hub.
+ It returns the name of the checkpoint.
+
+ Args:
+ task: The task for which
+ """
+ model = next(iter(list_models(filter="text-classification", sort="downloads", direction=-1)))
+ return model.id
+```
+
+该函数需要:
+- 一个清晰的名称。名称通常描述工具的功能。由于代码返回某个任务中下载次数最多的模型,因此我们将其命名为 `model_download_tool`。
+- 对输入和输出进行类型提示
+- 描述,其中包括 "`Args`:" 部分,描述每个参数(这次不需要类型指示,它会从类型提示中获取)。
+
+所有这些将自动嵌入到智能体的系统提示中,因此请尽量使它们尽可能清晰!
+
+> [TIP]
+> 这个定义格式与 apply_chat_template 中使用的工具模式相同,唯一的区别是添加了 tool 装饰器:可以在我们的工具使用 API 中[了解更多](https://huggingface.co/blog/unified-tool-use#passing-tools-to-a-chat-template).
+
+然后,您可以直接初始化您的智能体:
+```py
+from transformers import CodeAgent
+agent = CodeAgent(tools=[model_download_tool], llm_engine=llm_engine)
+agent.run(
+ "Can you give me the name of the model that has the most downloads in the 'text-to-video' task on the Hugging Face Hub?"
+)
+```
+
+您将得到以下输出:
+```text
+======== New task ========
+Can you give me the name of the model that has the most downloads in the 'text-to-video' task on the Hugging Face Hub?
+==== Agent is executing the code below:
+most_downloaded_model = model_download_tool(task="text-to-video")
+print(f"The most downloaded model for the 'text-to-video' task is {most_downloaded_model}.")
+====
+```
+
+输出:
+`"The most downloaded model for the 'text-to-video' task is ByteDance/AnimateDiff-Lightning."`
+
+### 管理智能体的工具箱
+
+如果您已经初始化了一个智能体,但想添加一个新的工具,重新初始化智能体会很麻烦。借助 Transformers,您可以通过添加或替换工具来管理智能体的工具箱。
+
+让我们将 `model_download_tool` 添加到一个仅初始化了默认工具箱的现有智能体中。
+
+```python
+from transformers import CodeAgent
+
+agent = CodeAgent(tools=[], llm_engine=llm_engine, add_base_tools=True)
+agent.toolbox.add_tool(model_download_tool)
+```
+现在,我们可以同时使用新工具和之前的文本到语音工具:
+
+```python
+agent.run(
+ "Can you read out loud the name of the model that has the most downloads in the 'text-to-video' task on the Hugging Face Hub and return the audio?"
+)
+```
+
+
+| **Audio** |
+|------------------------------------------------------------------------------------------------------------------------------------------------------|
+|
 +
 +
 +
 +
 +
 +
 +
 +
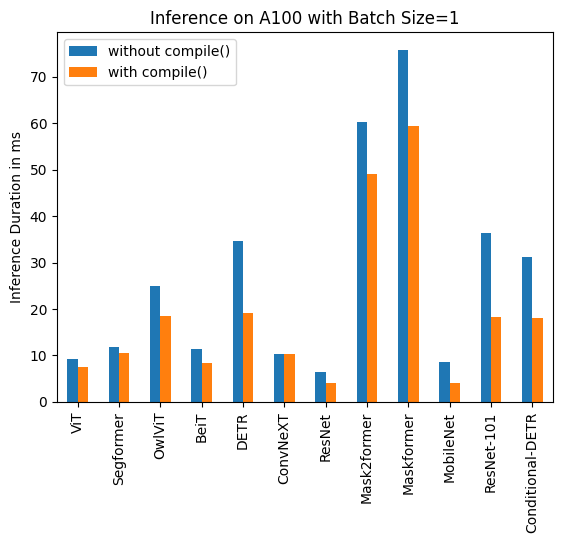 +
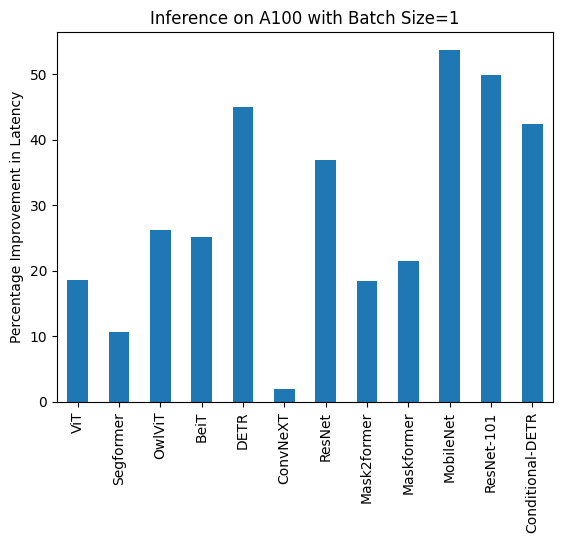 +
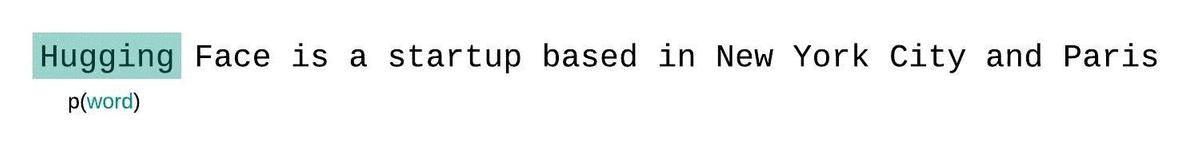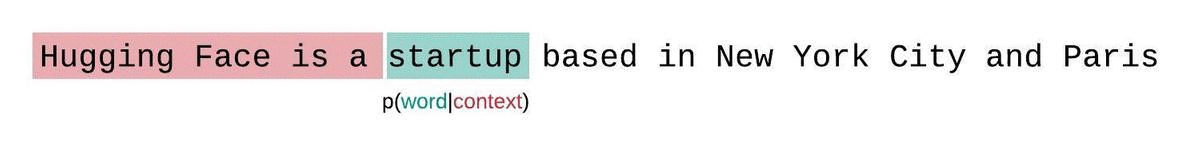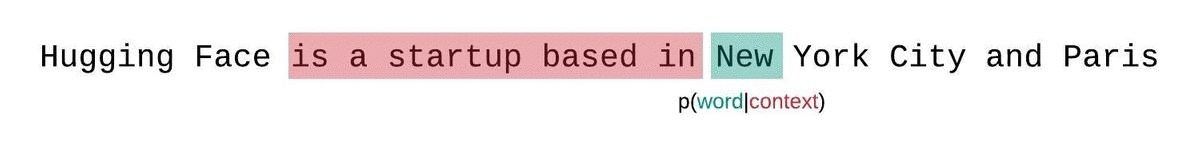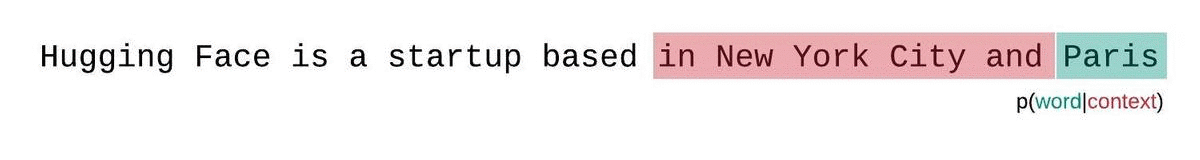 +
+これはシーケンスの確率のより正確な分解に近いものであり、通常はより有利なスコアを生成します。欠点は、コーパス内の各トークンに対して別個の前方パスが必要です。実用的な妥協案は、1トークンずつスライドする代わりに、より大きなストライドでコンテキストを移動するストライド型のスライディングウィンドウを使用することです。これにより、計算がはるかに高速に進行できる一方で、モデルには各ステップで予測を行うための大きなコンテキストが提供されます。
+
+## Example: Calculating perplexity with GPT-2 in 🤗 Transformers
+
+GPT-2を使用してこのプロセスをデモンストレーションしてみましょう。
+
+```python
+from transformers import GPT2LMHeadModel, GPT2TokenizerFast
+
+device = "cuda"
+model_id = "openai-community/gpt2-large"
+model = GPT2LMHeadModel.from_pretrained(model_id).to(device)
+tokenizer = GPT2TokenizerFast.from_pretrained(model_id)
+```
+
+WikiText-2データセットを読み込み、異なるスライディングウィンドウ戦略を使用してパープレキシティを評価します。このデータセットは小規模で、セット全体に対して単一のフォワードパスを実行するだけなので、データセット全体をメモリに読み込んでエンコードするだけで十分です。
+
+
+```python
+from datasets import load_dataset
+
+test = load_dataset("wikitext", "wikitext-2-raw-v1", split="test")
+encodings = tokenizer("\n\n".join(test["text"]), return_tensors="pt")
+```
+
+🤗 Transformersを使用すると、単純に`input_ids`をモデルの`labels`として渡すことで、各トークンの平均負の対数尤度が損失として返されます。しかし、スライディングウィンドウのアプローチでは、各イテレーションでモデルに渡すトークンにオーバーラップがあります。私たちは、コンテキストとして扱っているトークンの対数尤度を損失に含めたくありません。そのため、これらの対象を `-100` に設定して無視されるようにします。以下は、ストライドを `512` とした場合の例です。これにより、モデルは任意のトークンの条件付けの尤度を計算する際に、少なくともコンテキストとして 512 トークンを持つことになります(512 個の前のトークンが利用可能である場合)。
+
+
+```python
+import torch
+from tqdm import tqdm
+
+max_length = model.config.n_positions
+stride = 512
+seq_len = encodings.input_ids.size(1)
+
+nlls = []
+prev_end_loc = 0
+for begin_loc in tqdm(range(0, seq_len, stride)):
+ end_loc = min(begin_loc + max_length, seq_len)
+ trg_len = end_loc - prev_end_loc # may be different from stride on last loop
+ input_ids = encodings.input_ids[:, begin_loc:end_loc].to(device)
+ target_ids = input_ids.clone()
+ target_ids[:, :-trg_len] = -100
+
+ with torch.no_grad():
+ outputs = model(input_ids, labels=target_ids)
+
+ # loss is calculated using CrossEntropyLoss which averages over valid labels
+ # N.B. the model only calculates loss over trg_len - 1 labels, because it internally shifts the labels
+ # to the left by 1.
+ neg_log_likelihood = outputs.loss
+
+ nlls.append(neg_log_likelihood)
+
+ prev_end_loc = end_loc
+ if end_loc == seq_len:
+ break
+
+ppl = torch.exp(torch.stack(nlls).mean())
+```
+
+ストライド長が最大入力長と同じ場合、上述の最適でないスライディングウィンドウ戦略と同等です。ストライドが小さいほど、モデルは各予測を行う際により多くのコンテキストを持つため、通常、報告される困難度(perplexity)が向上します。
+
+上記のコードを `stride = 1024` で実行すると、オーバーラップがない状態で、結果の困難度(perplexity)は `19.44` になります。これは GPT-2 の論文に報告された `19.93` とほぼ同等です。一方、`stride = 512` を使用し、このようにストライディングウィンドウ戦略を採用すると、困難度(perplexity)が `16.45` に向上します。これはより好意的なスコアだけでなく、シーケンスの尤度の真の自己回帰分解により近い方法で計算されています。
+
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/philosophy.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/philosophy.md
new file mode 100644
index 0000000000000000000000000000000000000000..3edef0bd2add3b20d37332d0afadb904214ab1b0
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/philosophy.md
@@ -0,0 +1,67 @@
+
+
+# Philosophy
+
+🤗 Transformersは、次のような目的で構築された意見を持つライブラリです:
+
+- 大規模なTransformersモデルを使用、研究、または拡張したい機械学習研究者および教育者。
+- これらのモデルを微調整したり、本番環境で提供したり、またはその両方を行いたい実務家。
+- 与えられた機械学習タスクを解決するために、事前トレーニングされたモデルをダウンロードして使用したいエンジニア。
+
+このライブラリは、2つの強力な目標を持って設計されました:
+
+1. できるだけ簡単かつ高速に使用できるようにすること:
+
+ - ユーザー向けの抽象化を限りなく少なくし、実際、ほとんどの場合、抽象化はありません。
+ 各モデルを使用するために必要な3つの標準クラスだけが存在します:[構成](main_classes/configuration)、
+ [モデル](main_classes/model)、および前処理クラス(NLP用の[トークナイザ](main_classes/tokenizer)、ビジョン用の[イメージプロセッサ](main_classes/image_processor)、
+ オーディオ用の[特徴抽出器](main_classes/feature_extractor)、およびマルチモーダル入力用の[プロセッサ](main_classes/processors))。
+ - これらのクラスは、共通の`from_pretrained()`メソッドを使用して、事前トレーニング済みのインスタンスから簡単かつ統一された方法で初期化できます。このメソッドは、事前トレーニング済みのチェックポイントから関連するクラスのインスタンスと関連データ(構成のハイパーパラメータ、トークナイザの語彙、モデルの重み)をダウンロード(必要な場合はキャッシュ)して読み込みます。これらの基本クラスの上に、ライブラリは2つのAPIを提供しています:[パイプライン]は、特定のタスクでモデルをすばやく推論に使用するためのものであり、[`Trainer`]はPyTorchモデルを迅速にトレーニングまたは微調整するためのものです(すべてのTensorFlowモデルは`Keras.fit`と互換性があります)。
+ - その結果、このライブラリはニューラルネットワークのモジュラーツールボックスではありません。ライブラリを拡張または構築したい場合は、通常のPython、PyTorch、TensorFlow、Kerasモジュールを使用し、ライブラリの基本クラスから継承してモデルの読み込みと保存などの機能を再利用するだけです。モデルのコーディング哲学について詳しく知りたい場合は、[Repeat Yourself](https://huggingface.co/blog/transformers-design-philosophy)ブログ投稿をチェックしてみてください。
+
+2. オリジナルのモデルにできるだけ近い性能を持つ最新のモデルを提供すること:
+
+ - 各アーキテクチャに対して、公式な著者から提供された結果を再現する少なくとも1つの例を提供します。
+ - コードは通常、可能な限り元のコードベースに近いものであり、これはPyTorchコードがTensorFlowコードに変換されることから生じ、逆もまた然りです。
+
+その他のいくつかの目標:
+
+- モデルの内部をできるだけ一貫して公開すること:
+
+ - フルな隠れ状態と注意の重みにアクセスできる単一のAPIを提供します。
+ - 前処理クラスと基本モデルのAPIは標準化され、簡単にモデル間を切り替えることができます。
+
+- これらのモデルの微調整と調査のための有望なツールを主観的に選定すること:
+
+ - 語彙と埋め込みに新しいトークンを追加するための簡単で一貫した方法。
+ - Transformerヘッドをマスクおよびプルーンするための簡単な方法。
+
+- PyTorch、TensorFlow 2.0、およびFlaxの間を簡単に切り替えて、1つのフレームワークでトレーニングし、別のフレームワークで推論を行うことを可能にすること。
+
+## Main concepts
+
+このライブラリは、各モデルについて次の3つのタイプのクラスを中心に構築されています:
+
+- **モデルクラス**は、ライブラリで提供される事前トレーニング済みの重みと互換性のあるPyTorchモデル([torch.nn.Module](https://pytorch.org/docs/stable/nn.html#torch.nn.Module))、Kerasモデル([tf.keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model))またはJAX/Flaxモデル([flax.linen.Module](https://flax.readthedocs.io/en/latest/api_reference/flax.linen/module.html))を使用できます。
+- **構成クラス**は、モデルを構築するために必要なハイパーパラメータを格納します(層の数や隠れ層のサイズなど)。これらを自分でインスタンス化する必要はありません。特に、変更を加えずに事前トレーニング済みモデルを使用している場合、モデルを作成すると自動的に構成がインスタンス化されるようになります(これはモデルの一部です)。
+- **前処理クラス**は、生データをモデルが受け入れる形式に変換します。[トークナイザ](main_classes/tokenizer)は各モデルの語彙を保存し、文字列をトークン埋め込みのインデックスのリストにエンコードおよびデコードするためのメソッドを提供します。[イメージプロセッサ](main_classes/image_processor)はビジョン入力を前処理し、[特徴抽出器](main_classes/feature_extractor)はオーディオ入力を前処理し、[プロセッサ](main_classes/processors)はマルチモーダル入力を処理します。
+
+これらのすべてのクラスは、事前トレーニング済みのインスタンスからインスタンス化し、ローカルに保存し、Hubで共有することができる3つのメソッドを使用しています:
+
+- `from_pretrained()`は、ライブラリ自体によって提供される([モデルハブ](https://huggingface.co/models)でサポートされているモデルがあります)か、ユーザーによってローカルに保存された(またはサーバーに保存された)事前トレーニング済みバージョンからモデル、構成、前処理クラスをインスタンス化するためのメソッドです。
+- `save_pretrained()`は、モデル、構成、前処理クラスをローカルに保存し、`from_pretrained()`を使用して再読み込みできるようにします。
+- `push_to_hub()`は、モデル、構成、前処理クラスをHubに共有し、誰でも簡単にアクセスできるようにします。
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/pipeline_tutorial.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/pipeline_tutorial.md
new file mode 100644
index 0000000000000000000000000000000000000000..5dbda5ce4d4a359b9ae0a1f5be9714feb18b6ea5
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ja/pipeline_tutorial.md
@@ -0,0 +1,295 @@
+
+
+# Pipelines for inference
+
+[`pipeline`]を使用することで、[Hub](https://huggingface.co/models)からの任意のモデルを言語、コンピュータビジョン、音声、およびマルチモーダルタスクの推論に簡単に使用できます。
+特定のモダリティに関する経験がない場合や、モデルの背後にあるコードに精通していない場合でも、[`pipeline`]を使用して推論できます!
+このチュートリアルでは、次のことを学びます:
+
+- 推論のための[`pipeline`]の使用方法。
+- 特定のトークナイザやモデルの使用方法。
+- オーディオ、ビジョン、マルチモーダルタスクのための[`pipeline`]の使用方法。
+
+
 +
 +
 +
 +
 +
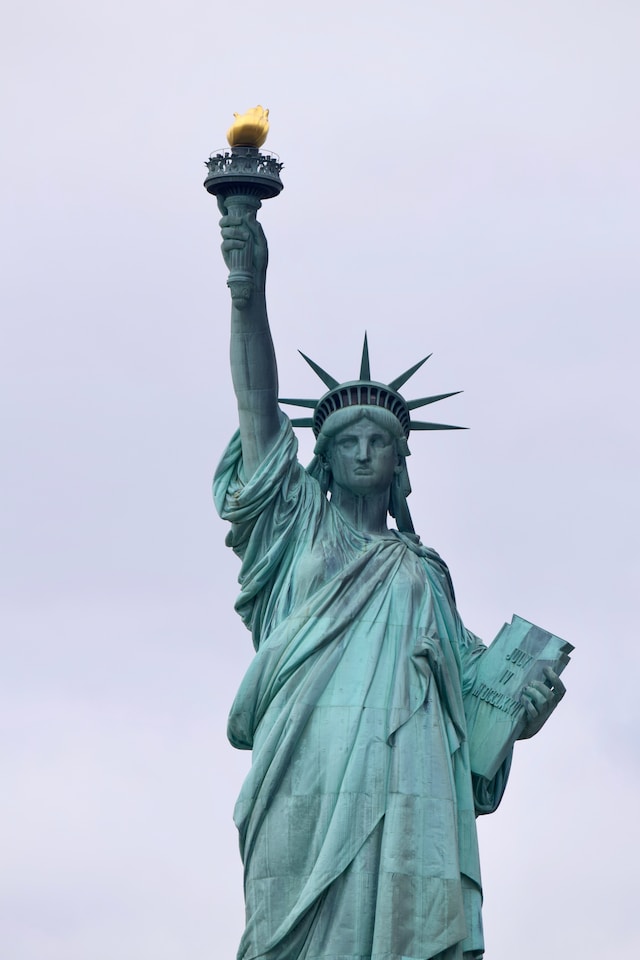 +
 +
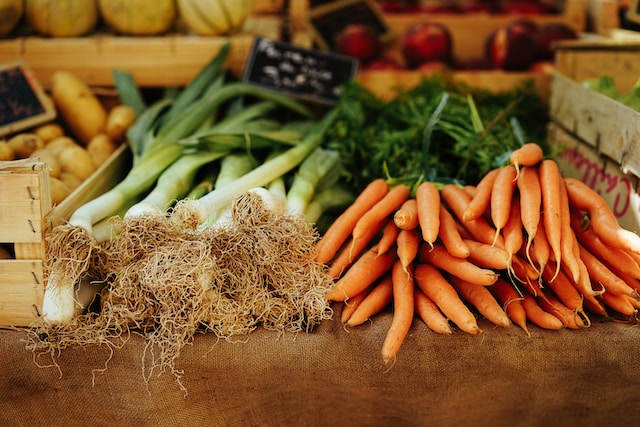 +
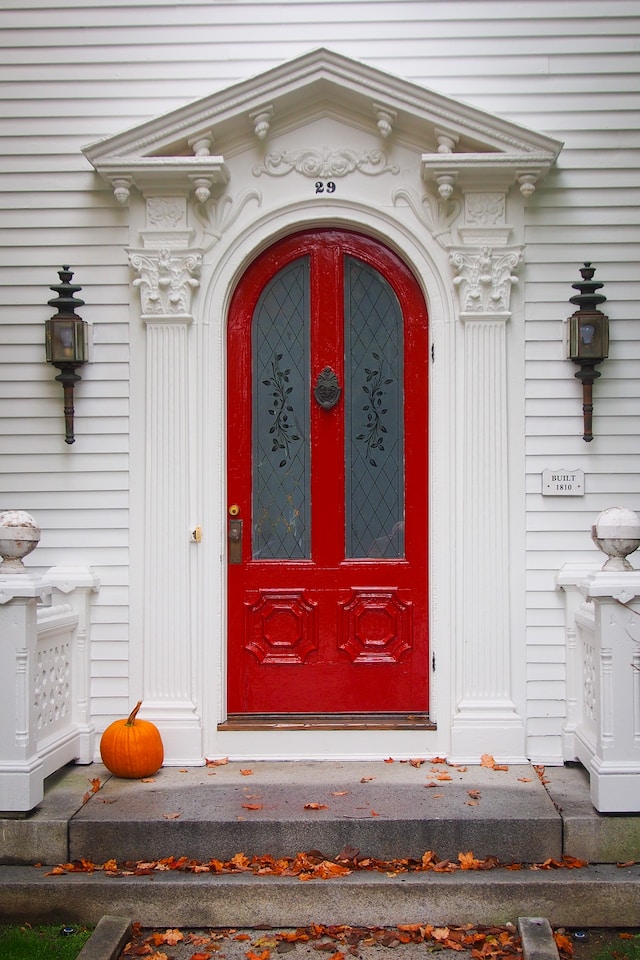 +
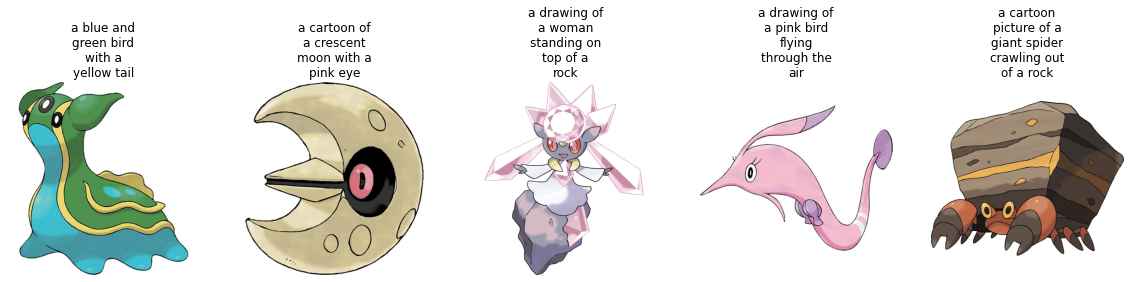 +
 +
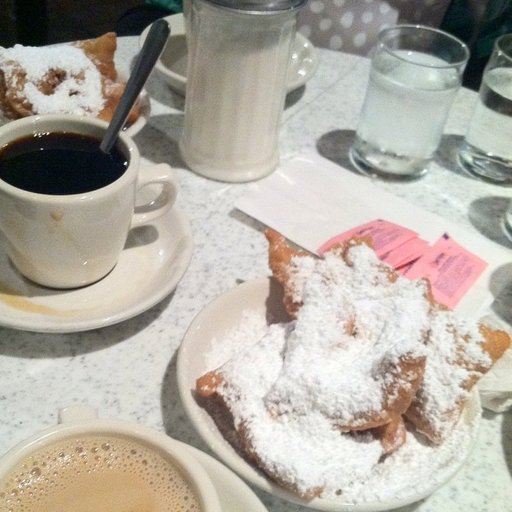 +
 +
 +
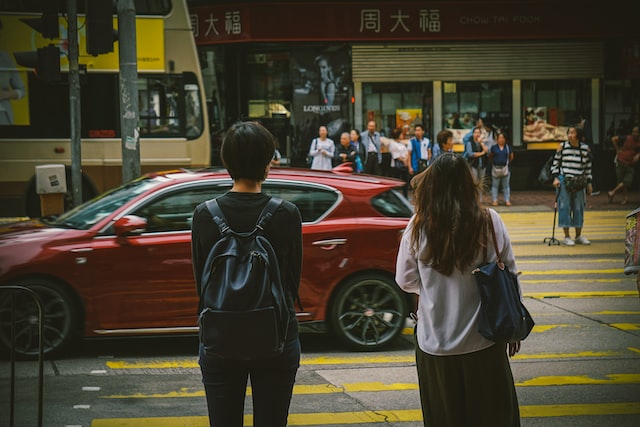 +
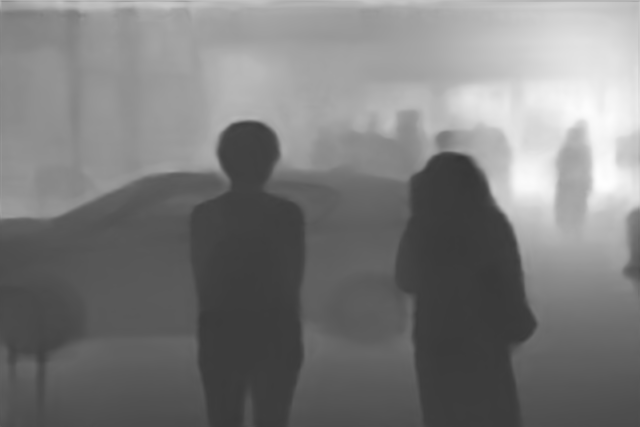 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
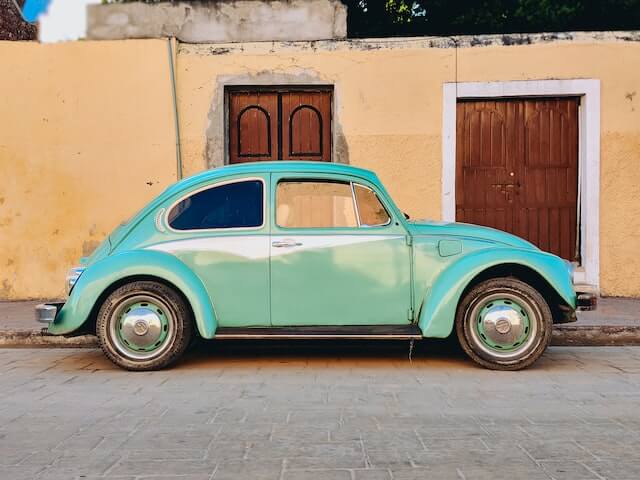 +
 +
 +
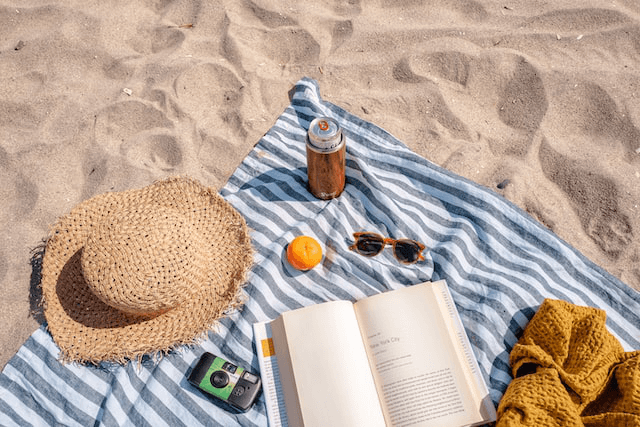 +
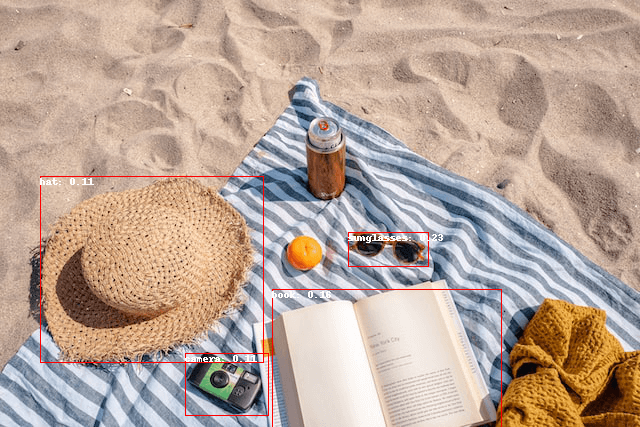 +
 +
 +
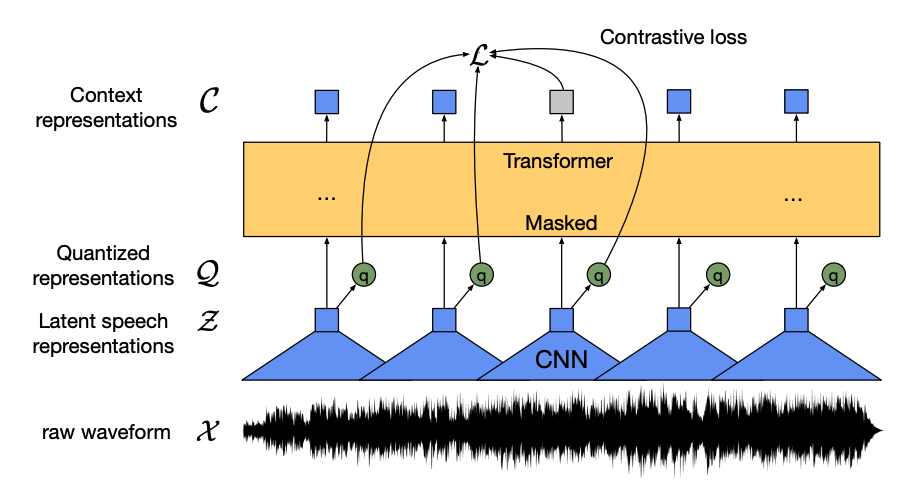 +
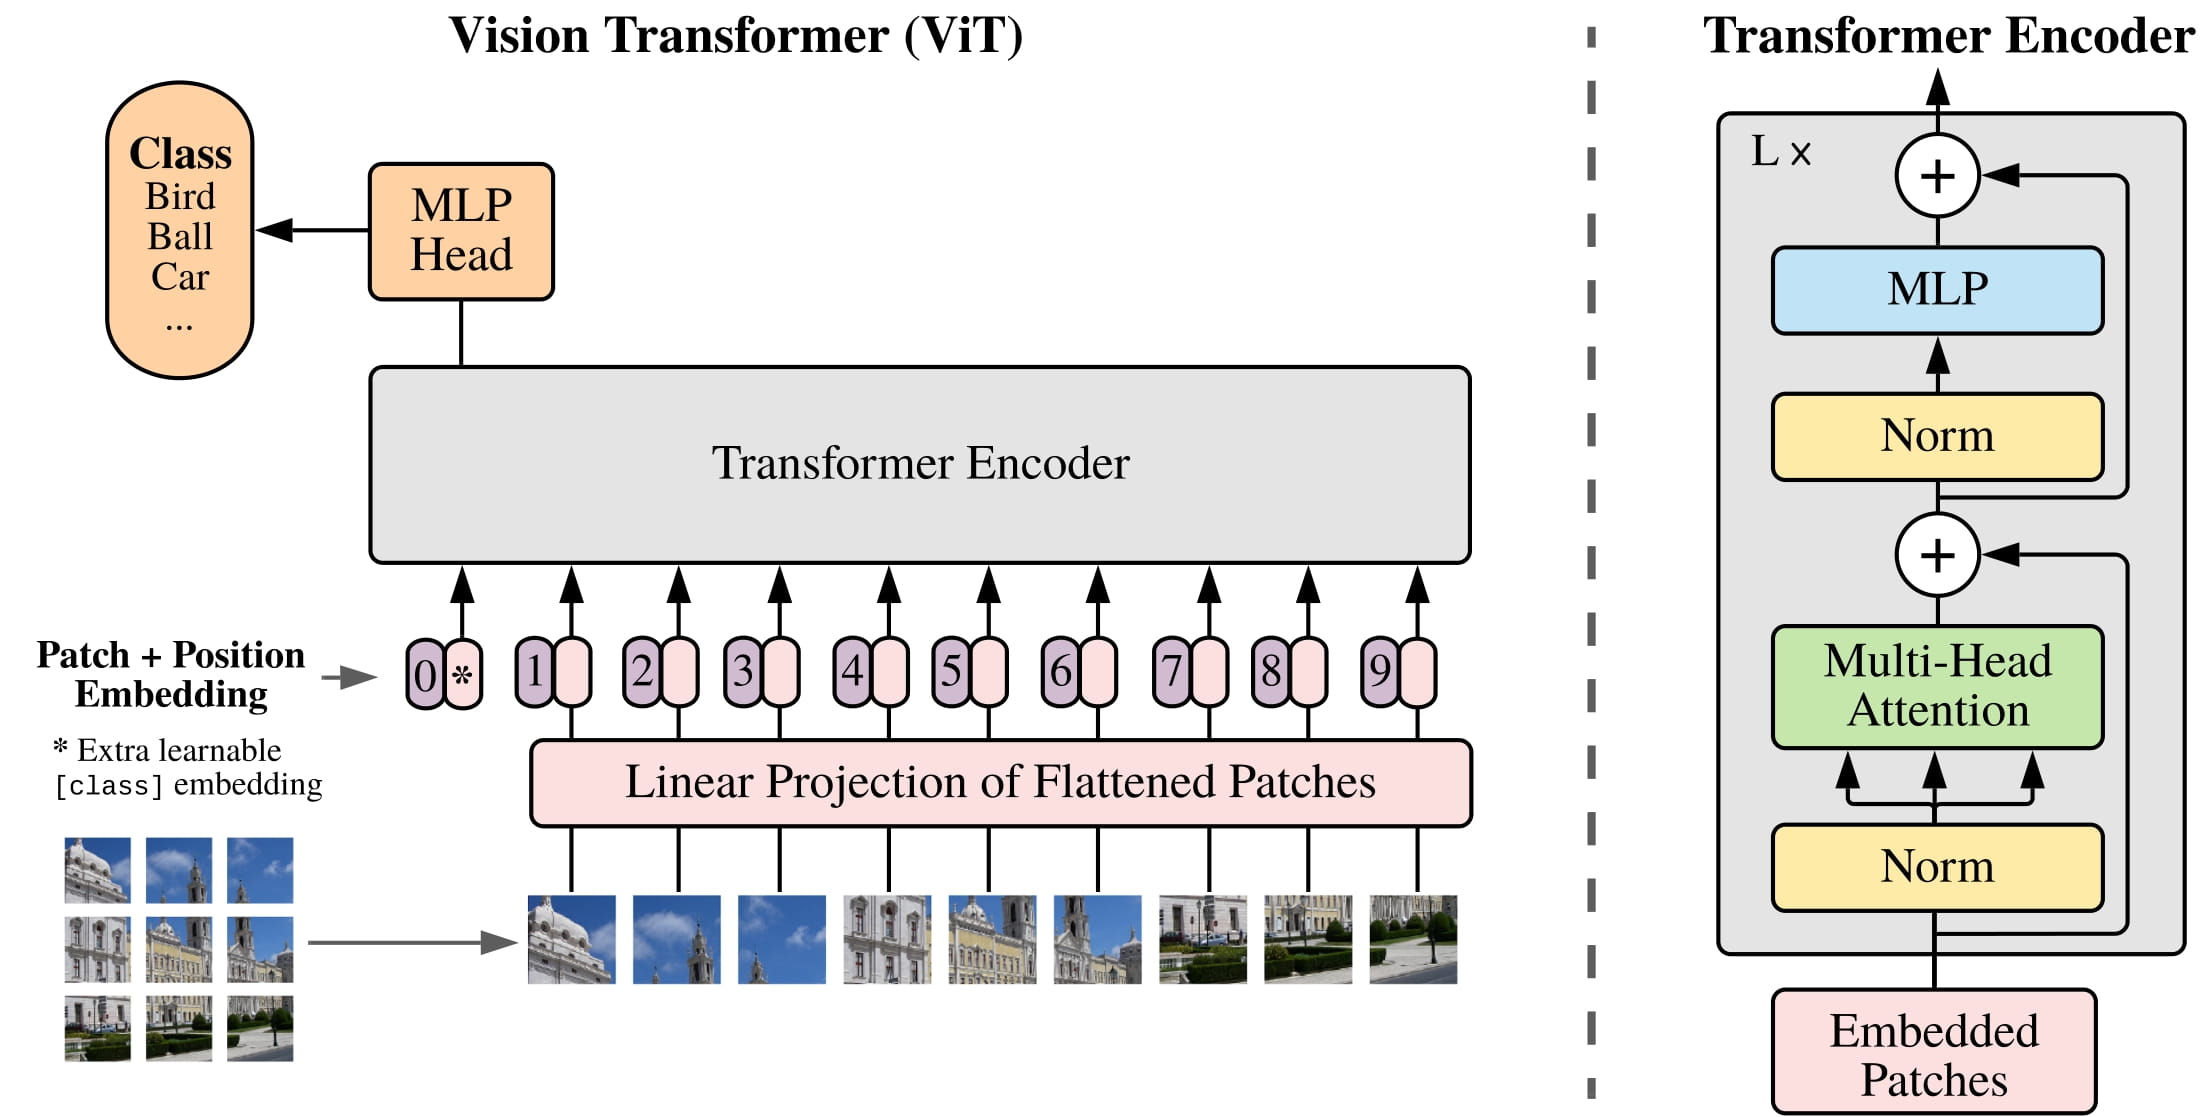 +
 +
 +
 +
 +
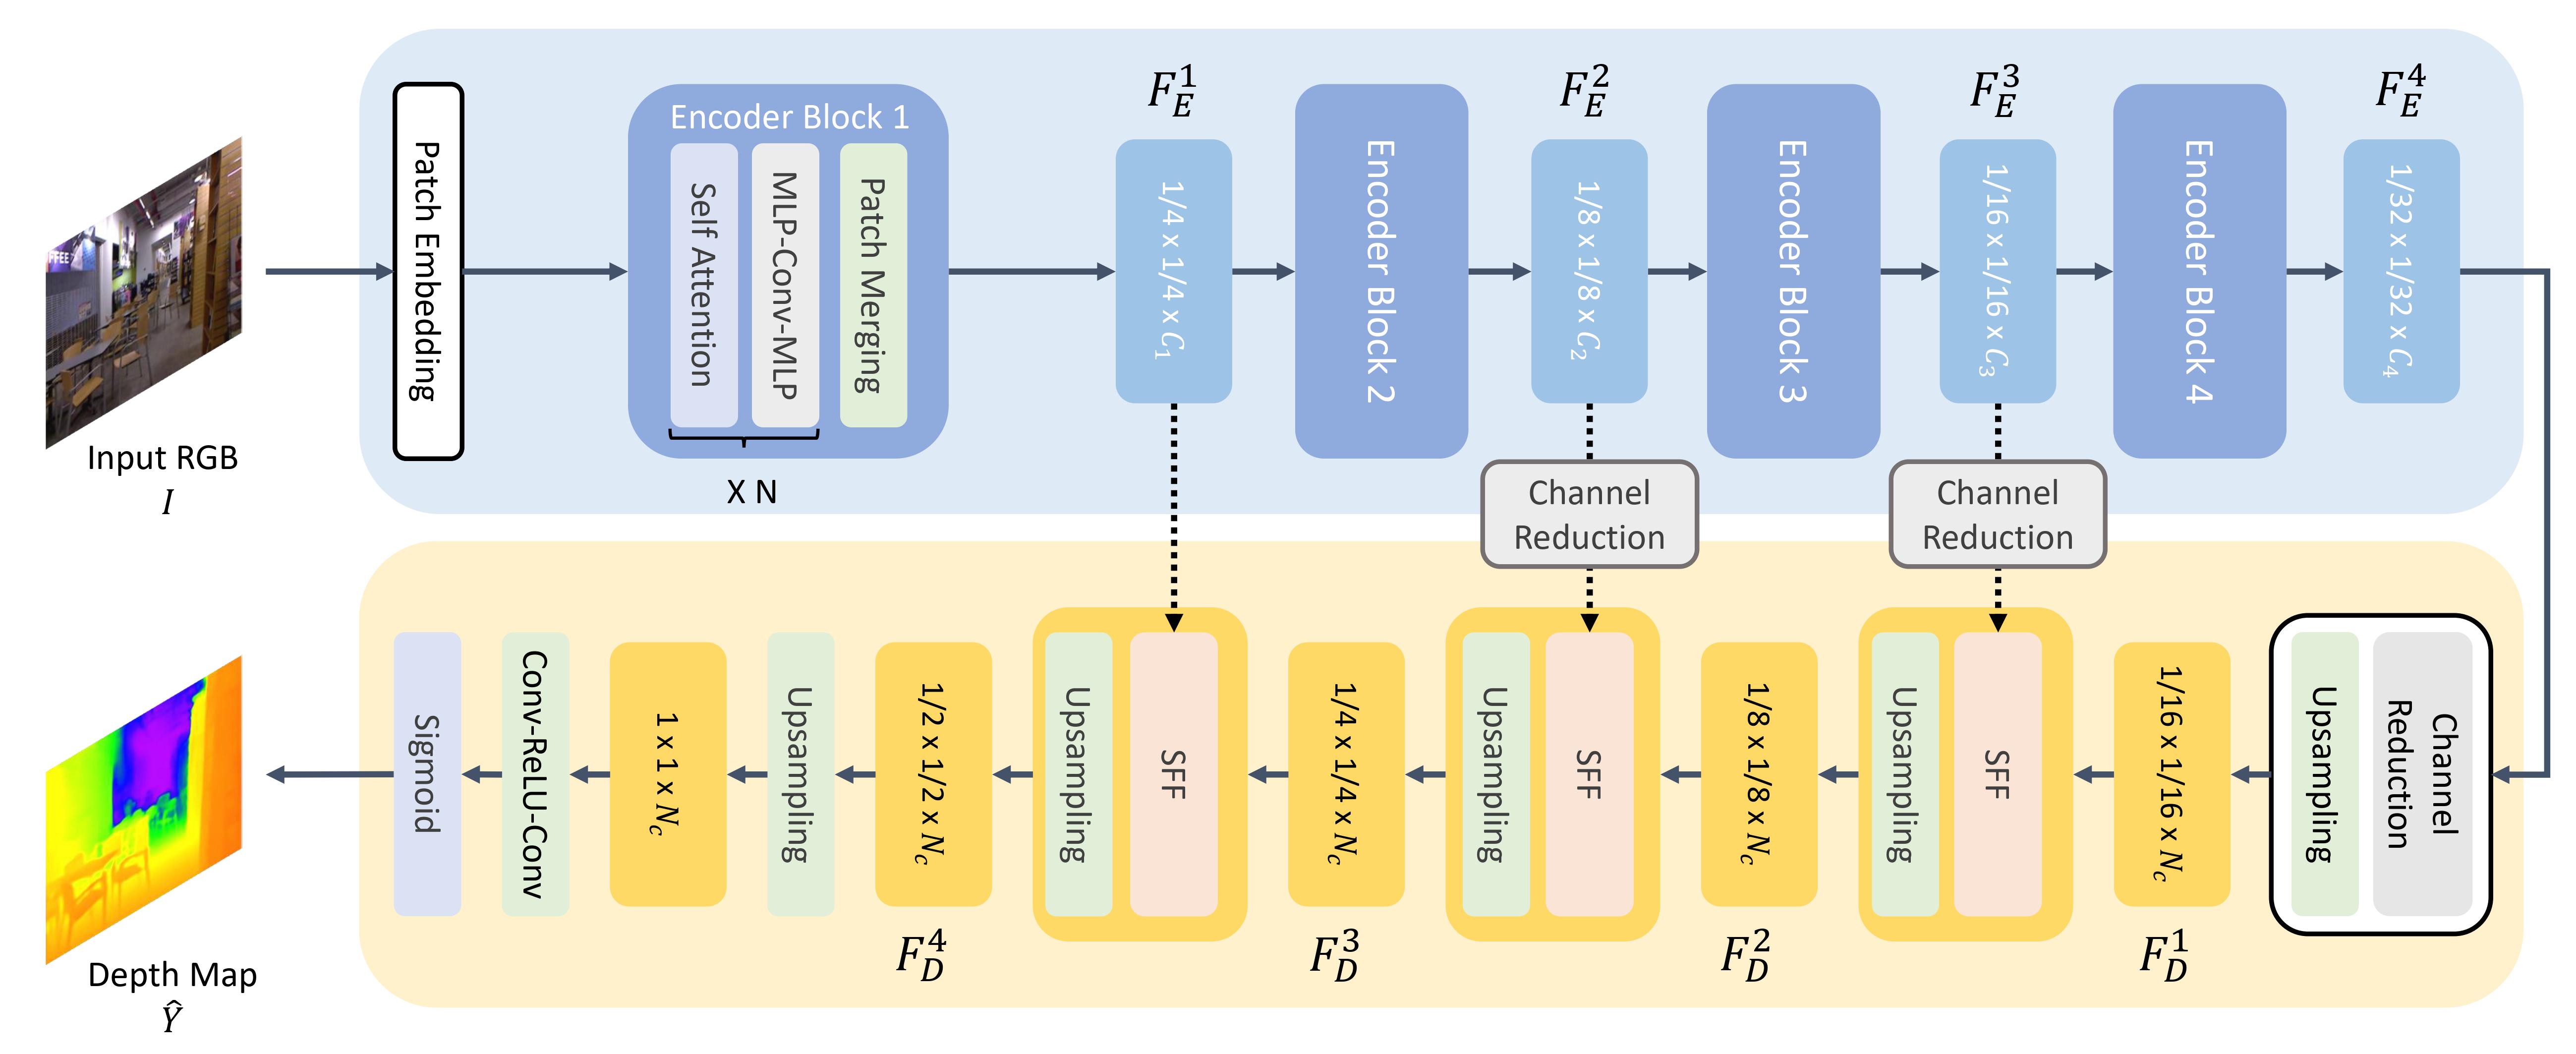 +
 +
 +
 | A beaver is swimming in the water |
+
+---
+
+```py
+agent.run("Read the following text out loud", text=text)
+```
+| **Input** | **Output** |
+|-------------------------------------------------------------------------------------------------------------------------|----------------------------------------------|
+| A beaver is swimming in the water |
+
+---
+
+```py
+agent.run(
+ "In the following `document`, where will the TRRF Scientific Advisory Council Meeting take place?",
+ document=document,
+)
+```
+| **Input** | **Output** |
+|-----------------------------------------------------------------------------------------------------------------------------|----------------|
+|
 | ballroom foyer |
+
+## Quickstart
+
+`agent.run`を使用する前に、エージェントをインスタンス化する必要があります。エージェントは、大規模な言語モデル(LLM)です。
+OpenAIモデルとBigCode、OpenAssistantからのオープンソースの代替モデルをサポートしています。OpenAIモデルはパフォーマンスが優れていますが、OpenAIのAPIキーが必要であり、無料で使用することはできません。一方、Hugging FaceはBigCodeとOpenAssistantモデルのエンドポイントへの無料アクセスを提供しています。
+
+まず、デフォルトの依存関係をすべてインストールするために`agents`のエクストラをインストールしてください。
+
+
+```bash
+pip install transformers[agents]
+```
+
+OpenAIモデルを使用するには、`openai`の依存関係をインストールした後、`OpenAiAgent`をインスタンス化します。
+
+
+```bash
+pip install openai
+```
+
+
+```py
+from transformers import OpenAiAgent
+
+agent = OpenAiAgent(model="text-davinci-003", api_key="
 +
+
+これは、実行したいタスクに適したツール(またはツール)を自動的に選択し、適切に実行します。1つまたは複数のタスクを同じ命令で実行することができます(ただし、命令が複雑であるほど、エージェントが失敗する可能性が高くなります)。
+
+
+```py
+agent.run("Draw me a picture of the sea then transform the picture to add an island")
+```
+
+
 +
+
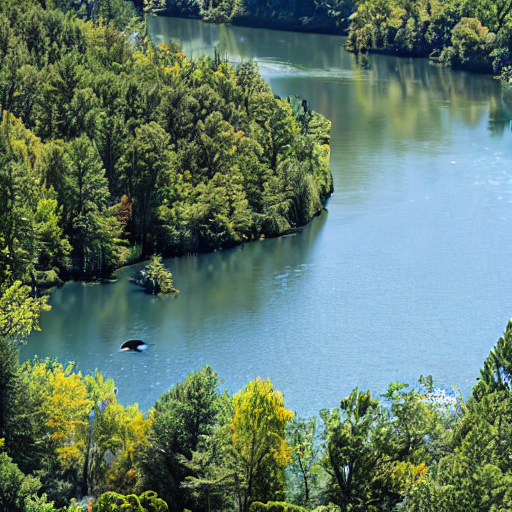 +
+
 +
+보다시피, 🤗 Transformers에서는 상속을 사용하지만 추상화 수준을 최소한으로 유지합니다. 라이브러리의 어떤 모델에서도 두 수준 이상의 추상화가 존재하지 않습니다. `BrandNewBertModel`은 `BrandNewBertPreTrainedModel`에서 상속받고, 이 클래스는 [`PreTrainedModel`]에서 상속받습니다. 이로써 새로운 모델은 [`PreTrainedModel`]에만 의존하도록 하려고 합니다. 모든 새로운 모델에 자동으로 제공되는 중요한 기능은 [`~PreTrainedModel.from_pretrained`] 및 [`~PreTrainedModel.save_pretrained`]입니다. 이러한 기능 외에도 `BrandNewBertModel.forward`와 같은 다른 중요한 기능은 새로운 `modeling_brand_new_bert.py` 스크립트에서 완전히 정의되어야 합니다. 또한 `BrandNewBertForMaskedLM`과 같은 특정 헤드 레이어를 가진 모델은 `BrandNewBertModel`을 상속받지 않고 forward pass에서 호출할 수 있는 `BrandNewBertModel`을 사용하여 추상화 수준을 낮게 유지합니다. 모든 새로운 모델은 `BrandNewBertConfig`라는 구성 클래스를 필요로 합니다. 이 구성은 항상 [`PreTrainedModel`]의 속성으로 저장되며, 따라서 `BrandNewBertPreTrainedModel`을 상속받는 모든 클래스에서 `config` 속성을 통해 액세스할 수 있습니다:
+
+```python
+model = BrandNewBertModel.from_pretrained("brandy/brand_new_bert")
+model.config # model has access to its config
+```
+
+모델과 마찬가지로 구성은 [`PretrainedConfig`]에서 기본 직렬화 및 역직렬화 기능을 상속받습니다. 구성과 모델은 항상 *pytorch_model.bin* 파일과 *config.json* 파일로 각각 별도로 직렬화됩니다. [`~PreTrainedModel.save_pretrained`]를 호출하면 자동으로 [`~PretrainedConfig.save_pretrained`]도 호출되므로 모델과 구성이 모두 저장됩니다.
+
+
+### 코드 스타일 [[code-style]]
+
+새로운 모델을 작성할 때, Transformers는 주관적인 라이브러리이며 몇 가지 독특한 코딩 스타일이 있습니다:
+
+1. 모델의 forward pass는 모델 파일에 완전히 작성되어야 합니다. 라이브러리의 다른 모델에서 블록을 재사용하려면 코드를 복사하여 위에 `# Copied from` 주석과 함께 붙여넣으면 됩니다 (예: [여기](https://github.com/huggingface/transformers/blob/v4.17.0/src/transformers/models/roberta/modeling_roberta.py#L160)를 참조하세요).
+2. 코드는 완전히 이해하기 쉬워야 합니다. 변수 이름을 명확하게 지정하고 약어를 사용하지 않는 것이 좋습니다. 예를 들어, `act`보다는 `activation`을 선호합니다. 한 글자 변수 이름은 루프의 인덱스인 경우를 제외하고 권장되지 않습니다.
+3. 더 일반적으로, 짧은 마법 같은 코드보다는 길고 명시적인 코드를 선호합니다.
+4. PyTorch에서 `nn.Sequential`을 하위 클래스로 만들지 말고 `nn.Module`을 하위 클래스로 만들고 forward pass를 작성하여 다른 사람이 코드를 빠르게 디버그할 수 있도록 합니다. print 문이나 중단점을 추가할 수 있습니다.
+5. 함수 시그니처에는 타입 주석을 사용해야 합니다. 그 외에는 타입 주석보다 변수 이름이 훨씬 읽기 쉽고 이해하기 쉽습니다.
+
+### 토크나이저 개요 [[overview-of-tokenizers]]
+
+아직 준비되지 않았습니다 :-( 이 섹션은 곧 추가될 예정입니다!
+
+## 🤗 Transformers에 모델 추가하는 단계별 방법 [[stepbystep-recipe-to-add-a-model-to-transformers]]
+
+각자 모델을 이식하는 방법에 대한 선호가 다르기 때문에 다른 기여자들이 Hugging Face에 모델을 이식하는 방법에 대한 요약을 살펴보는 것이 매우 유용할 수 있습니다. 다음은 모델을 이식하는 방법에 대한 커뮤니티 블로그 게시물 목록입니다:
+
+1. [GPT2 모델 이식하기](https://medium.com/huggingface/from-tensorflow-to-pytorch-265f40ef2a28) - [Thomas](https://huggingface.co/thomwolf)
+2. [WMT19 MT 모델 이식하기](https://huggingface.co/blog/porting-fsmt) - [Stas](https://huggingface.co/stas)
+
+경험상 모델을 추가할 때 주의해야 할 가장 중요한 사항은 다음과 같습니다:
+
+- 같은 일을 반복하지 마세요! 새로운 🤗 Transformers 모델을 위해 추가할 코드의 대부분은 이미 🤗 Transformers 어딘가에 존재합니다. 이미 존재하는 복사할 수 있는 유사한 모델과 토크나이저를 찾는데 시간을 투자하세요. [grep](https://www.gnu.org/software/grep/)와 [rg](https://github.com/BurntSushi/ripgrep)를 참고하세요. 모델의 토크나이저가 한 모델을 기반으로 하고 모델링 코드가 다른 모델을 기반으로 하는 경우가 존재할 수도 있습니다. 예를 들어 FSMT의 모델링 코드는 BART를 기반으로 하고 FSMT의 토크나이저 코드는 XLM을 기반으로 합니다.
+- 이것은 과학적인 도전보다는 공학적인 도전입니다. 논문의 모델의 모든 이론적 측면을 이해하려는 것보다 효율적인 디버깅 환경을 만드는 데 더 많은 시간을 소비해야 합니다.
+- 막힐 때 도움을 요청하세요! 모델은 🤗 Transformers의 핵심 구성 요소이므로 Hugging Face의 우리는 당신이 모델을 추가하는 각 단계에서 기꺼이 도움을 줄 준비가 되어 있습니다. 진전이 없다고 느끼면 주저하지 말고 도움을 요청하세요.
+
+다음에서는 모델을 🤗 Transformers로 이식하는 데 가장 유용한 일반적인 절차를 제공하려고 노력합니다.
+
+다음 목록은 모델을 추가하는 데 수행해야 할 모든 작업의 요약이며 To-Do 목록으로 사용할 수 있습니다:
+
+☐ (선택 사항) BrandNewBert의 이론적 측면 이해
 +
 +
+
+## 콘텐츠[[contents]]
+
+저희 기술문서는 크게 5개 섹션으로 나눌 수 있습니다:
+
+- **시작하기**에서 라이브러리를 간단히 훑어보고, 본격적으로 뛰어들 수 있게 설치 방법을 안내합니다.
+- **튜토리얼**에서 라이브러리에 익숙해질 수 있도록 자세하고도 쉽게 기본적인 부분을 안내합니다.
+- **How-to 가이드**에서 언어 모델링을 위해 사전학습된 모델을 파인 튜닝하는 방법이나, 직접 모델을 작성하고 공유하는 방법과 같이 특정 목표를 달성하는 방법을 안내합니다.
+- **개념 가이드**에서 🤗 Transformers의 설계 철학과 함께 모델이나 태스크 뒤에 숨겨진 개념들과 아이디어를 탐구하고 설명을 덧붙입니다.
+- **API**에서 모든 클래스와 함수를 설명합니다.
+
+ - **메인 클래스**에서 configuration, model, tokenizer, pipeline과 같이 제일 중요한 클래스들을 자세히 설명합니다.
+ - **모델**에서 라이브러리 속 구현된 각 모델과 연관된 클래스와 함수를 자세히 설명합니다.
+ - **내부 유틸리티**에서 내부적으로 사용되는 유틸리티 클래스와 함수를 자세히 설명합니다.
+
+### 지원 모델[[supported-models]]
+
+
+
+1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
+1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
+1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
+1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
+1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
+1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
+1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
+1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BLOOM](model_doc/bloom)** (from BigScience workshop) released by the [BigScience Workshop](https://bigscience.huggingface.co/).
+1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499) by Adrian de Wynter and Daniel J. Perry.
+1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
+1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
+1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
+1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
+1. **[CLIPSeg](model_doc/clipseg)** (from University of Göttingen) released with the paper [Image Segmentation Using Text and Image Prompts](https://arxiv.org/abs/2112.10003) by Timo Lüddecke and Alexander Ecker.
+1. **[CodeGen](model_doc/codegen)** (from Salesforce) released with the paper [A Conversational Paradigm for Program Synthesis](https://arxiv.org/abs/2203.13474) by Erik Nijkamp, Bo Pang, Hiroaki Hayashi, Lifu Tu, Huan Wang, Yingbo Zhou, Silvio Savarese, Caiming Xiong.
+1. **[Conditional DETR](model_doc/conditional_detr)** (from Microsoft Research Asia) released with the paper [Conditional DETR for Fast Training Convergence](https://arxiv.org/abs/2108.06152) by Depu Meng, Xiaokang Chen, Zejia Fan, Gang Zeng, Houqiang Li, Yuhui Yuan, Lei Sun, Jingdong Wang.
+1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
+1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
+1. **[CvT](model_doc/cvt)** (from Microsoft) released with the paper [CvT: Introducing Convolutions to Vision Transformers](https://arxiv.org/abs/2103.15808) by Haiping Wu, Bin Xiao, Noel Codella, Mengchen Liu, Xiyang Dai, Lu Yuan, Lei Zhang.
+1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
+1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+1. **[Deformable DETR](model_doc/deformable_detr)** (from SenseTime Research) released with the paper [Deformable DETR: Deformable Transformers for End-to-End Object Detection](https://arxiv.org/abs/2010.04159) by Xizhou Zhu, Weijie Su, Lewei Lu, Bin Li, Xiaogang Wang, Jifeng Dai.
+1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
+1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
+1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
+1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) and a German version of DistilBERT.
+1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
+1. **[Donut](model_doc/donut)** (from NAVER), released together with the paper [OCR-free Document Understanding Transformer](https://arxiv.org/abs/2111.15664) by Geewook Kim, Teakgyu Hong, Moonbin Yim, Jeongyeon Nam, Jinyoung Park, Jinyeong Yim, Wonseok Hwang, Sangdoo Yun, Dongyoon Han, Seunghyun Park.
+1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
+1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+1. **[EfficientNet](model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://arxiv.org/abs/1905.11946) by Mingxing Tan and Quoc V. Le.
+1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
+1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[ERNIE](model_doc/ernie)** (from Baidu) released with the paper [ERNIE: Enhanced Representation through Knowledge Integration](https://arxiv.org/abs/1904.09223) by Yu Sun, Shuohuan Wang, Yukun Li, Shikun Feng, Xuyi Chen, Han Zhang, Xin Tian, Danxiang Zhu, Hao Tian, Hua Wu.
+1. **[ESM](model_doc/esm)** (from Meta AI) are transformer protein language models. **ESM-1b** was released with the paper [Biological structure and function emerge from scaling unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118) by Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott, C. Lawrence Zitnick, Jerry Ma, and Rob Fergus. **ESM-1v** was released with the paper [Language models enable zero-shot prediction of the effects of mutations on protein function](https://doi.org/10.1101/2021.07.09.450648) by Joshua Meier, Roshan Rao, Robert Verkuil, Jason Liu, Tom Sercu and Alexander Rives. **ESM-2 and ESMFold** were released with the paper [Language models of protein sequences at the scale of evolution enable accurate structure prediction](https://doi.org/10.1101/2022.07.20.500902) by Zeming Lin, Halil Akin, Roshan Rao, Brian Hie, Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido, Alexander Rives.
+1. **[FLAN-T5](model_doc/flan-t5)** (from Google AI) released in the repository [google-research/t5x](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-t5-checkpoints) by Hyung Won Chung, Le Hou, Shayne Longpre, Barret Zoph, Yi Tay, William Fedus, Eric Li, Xuezhi Wang, Mostafa Dehghani, Siddhartha Brahma, Albert Webson, Shixiang Shane Gu, Zhuyun Dai, Mirac Suzgun, Xinyun Chen, Aakanksha Chowdhery, Sharan Narang, Gaurav Mishra, Adams Yu, Vincent Zhao, Yanping Huang, Andrew Dai, Hongkun Yu, Slav Petrov, Ed H. Chi, Jeff Dean, Jacob Devlin, Adam Roberts, Denny Zhou, Quoc V. Le, and Jason Wei
+1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
+1. **[FLAVA](model_doc/flava)** (from Facebook AI) released with the paper [FLAVA: A Foundational Language And Vision Alignment Model](https://arxiv.org/abs/2112.04482) by Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela.
+1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
+1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
+1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
+1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
+1. **[GPT NeoX](model_doc/gpt_neox)** (from EleutherAI) released with the paper [GPT-NeoX-20B: An Open-Source Autoregressive Language Model](https://arxiv.org/abs/2204.06745) by Sid Black, Stella Biderman, Eric Hallahan, Quentin Anthony, Leo Gao, Laurence Golding, Horace He, Connor Leahy, Kyle McDonell, Jason Phang, Michael Pieler, USVSN Sai Prashanth, Shivanshu Purohit, Laria Reynolds, Jonathan Tow, Ben Wang, Samuel Weinbach
+1. **[GPT NeoX Japanese](model_doc/gpt_neox_japanese)** (from ABEJA) released by Shinya Otani, Takayoshi Makabe, Anuj Arora, and Kyo Hattori.
+1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
+1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
+1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released in the repository [tanreinama/GPTSAN](https://github.com/tanreinama/GPTSAN/blob/main/report/model.md) by Toshiyuki Sakamoto(tanreinama).
+1. **[GroupViT](model_doc/groupvit)** (from UCSD, NVIDIA) released with the paper [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://arxiv.org/abs/2202.11094) by Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang.
+1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
+1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
+1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
+1. **[Jukebox](model_doc/jukebox)** (from OpenAI) released with the paper [Jukebox: A Generative Model for Music](https://arxiv.org/pdf/2005.00341.pdf) by Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford, Ilya Sutskever.
+1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
+1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
+1. **[LayoutLMv3](model_doc/layoutlmv3)** (from Microsoft Research Asia) released with the paper [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://arxiv.org/abs/2204.08387) by Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
+1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
+1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LeViT](model_doc/levit)** (from Meta AI) released with the paper [LeViT: A Vision Transformer in ConvNet's Clothing for Faster Inference](https://arxiv.org/abs/2104.01136) by Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze.
+1. **[LiLT](model_doc/lilt)** (from South China University of Technology) released with the paper [LiLT: A Simple yet Effective Language-Independent Layout Transformer for Structured Document Understanding](https://arxiv.org/abs/2202.13669) by Jiapeng Wang, Lianwen Jin, Kai Ding.
+1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LongT5](model_doc/longt5)** (from Google AI) released with the paper [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://arxiv.org/abs/2112.07916) by Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung, Yinfei Yang.
+1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
+1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490) by Hao Tan and Mohit Bansal.
+1. **[M-CTC-T](model_doc/mctct)** (from Facebook) released with the paper [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://arxiv.org/abs/2111.00161) by Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert.
+1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
+1. **[MarkupLM](model_doc/markuplm)** (from Microsoft Research Asia) released with the paper [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document Understanding](https://arxiv.org/abs/2110.08518) by Junlong Li, Yiheng Xu, Lei Cui, Furu Wei.
+1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
+1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
+1. **[mBART](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+1. **[mBART-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
+1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
+1. **[MobileBERT](model_doc/mobilebert)** (from CMU/Google Brain) released with the paper [MobileBERT: a Compact Task-Agnostic BERT for Resource-Limited Devices](https://arxiv.org/abs/2004.02984) by Zhiqing Sun, Hongkun Yu, Xiaodan Song, Renjie Liu, Yiming Yang, and Denny Zhou.
+1. **[MobileViT](model_doc/mobilevit)** (from Apple) released with the paper [MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer](https://arxiv.org/abs/2110.02178) by Sachin Mehta and Mohammad Rastegari.
+1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
+1. **[MVP](model_doc/mvp)** (from RUC AI Box) released with the paper [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://arxiv.org/abs/2206.12131) by Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen.
+1. **[Nezha](model_doc/nezha)** (from Huawei Noah’s Ark Lab) released with the paper [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://arxiv.org/abs/1909.00204) by Junqiu Wei, Xiaozhe Ren, Xiaoguang Li, Wenyong Huang, Yi Liao, Yasheng Wang, Jiashu Lin, Xin Jiang, Xiao Chen and Qun Liu.
+1. **[NLLB](model_doc/nllb)** (from Meta) released with the paper [No Language Left Behind: Scaling Human-Centered Machine Translation](https://arxiv.org/abs/2207.04672) by the NLLB team.
+1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
+1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
+1. **[OPT](master/model_doc/opt)** (from Meta AI) released with the paper [OPT: Open Pre-trained Transformer Language Models](https://arxiv.org/abs/2205.01068) by Susan Zhang, Stephen Roller, Naman Goyal, Mikel Artetxe, Moya Chen, Shuohui Chen et al.
+1. **[OWL-ViT](model_doc/owlvit)** (from Google AI) released with the paper [Simple Open-Vocabulary Object Detection with Vision Transformers](https://arxiv.org/abs/2205.06230) by Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby.
+1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
+1. **[PEGASUS-X](model_doc/pegasus_x)** (from Google) released with the paper [Investigating Efficiently Extending Transformers for Long Input Summarization](https://arxiv.org/abs/2208.04347) by Jason Phang, Yao Zhao, and Peter J. Liu.
+1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
+1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
+1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
+1. **[RAG](model_doc/rag)** (from Facebook) released with the paper [Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks](https://arxiv.org/abs/2005.11401) by Patrick Lewis, Ethan Perez, Aleksandara Piktus, Fabio Petroni, Vladimir Karpukhin, Naman Goyal, Heinrich Küttler, Mike Lewis, Wen-tau Yih, Tim Rocktäschel, Sebastian Riedel, Douwe Kiela.
+1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
+1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://arxiv.org/abs/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
+1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
+1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
+1. **[RoCBert](model_doc/roc_bert)** (from WeChatAI) released with the paper [RoCBert: Robust Chinese Bert with Multimodal Contrastive Pretraining](https://aclanthology.org/2022.acl-long.65.pdf) by HuiSu, WeiweiShi, XiaoyuShen, XiaoZhou, TuoJi, JiaruiFang, JieZhou.
+1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
+1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
+1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
+1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
+1. **[SqueezeBERT](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
+1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+1. **[Swin Transformer V2](model_doc/swinv2)** (from Microsoft) released with the paper [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883) by Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo.
+1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[Table Transformer](model_doc/table-transformer)** (from Microsoft Research) released with the paper [PubTables-1M: Towards Comprehensive Table Extraction From Unstructured Documents](https://arxiv.org/abs/2110.00061) by Brandon Smock, Rohith Pesala, Robin Abraham.
+1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
+1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
+1. **[Time Series Transformer](model_doc/time_series_transformer)** (from HuggingFace).
+1. **[Trajectory Transformer](model_doc/trajectory_transformers)** (from the University of California at Berkeley) released with the paper [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://arxiv.org/abs/2106.02039) by Michael Janner, Qiyang Li, Sergey Levine
+1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
+1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
+1. **[UL2](model_doc/ul2)** (from Google Research) released with the paper [Unifying Language Learning Paradigms](https://arxiv.org/abs/2205.05131v1) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler
+1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
+1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
+1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://arxiv.org/abs/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+1. **[VideoMAE](model_doc/videomae)** (from Multimedia Computing Group, Nanjing University) released with the paper [VideoMAE: Masked Autoencoders are Data-Efficient Learners for Self-Supervised Video Pre-Training](https://arxiv.org/abs/2203.12602) by Zhan Tong, Yibing Song, Jue Wang, Limin Wang.
+1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
+1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
+1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
+1. **[ViTMSN](model_doc/vit_msn)** (from Meta AI) released with the paper [Masked Siamese Networks for Label-Efficient Learning](https://arxiv.org/abs/2204.07141) by Mahmoud Assran, Mathilde Caron, Ishan Misra, Piotr Bojanowski, Florian Bordes, Pascal Vincent, Armand Joulin, Michael Rabbat, Nicolas Ballas.
+1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
+1. **[Wav2Vec2-Conformer](model_doc/wav2vec2-conformer)** (from Facebook AI) released with the paper [FAIRSEQ S2T: Fast Speech-to-Text Modeling with FAIRSEQ](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Sravya Popuri, Dmytro Okhonko, Juan Pino.
+1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
+1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
+1. **[Whisper](model_doc/whisper)** (from OpenAI) released with the paper [Robust Speech Recognition via Large-Scale Weak Supervision](https://cdn.openai.com/papers/whisper.pdf) by Alec Radford, Jong Wook Kim, Tao Xu, Greg Brockman, Christine McLeavey, Ilya Sutskever.
+1. **[X-CLIP](model_doc/xclip)** (from Microsoft Research) released with the paper [Expanding Language-Image Pretrained Models for General Video Recognition](https://arxiv.org/abs/2208.02816) by Bolin Ni, Houwen Peng, Minghao Chen, Songyang Zhang, Gaofeng Meng, Jianlong Fu, Shiming Xiang, Haibin Ling.
+1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
+1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291) by Guillaume Lample and Alexis Conneau.
+1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
+1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
+1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
+1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
+1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
+1. **[YOLOS](model_doc/yolos)** (from Huazhong University of Science & Technology) released with the paper [You Only Look at One Sequence: Rethinking Transformer in Vision through Object Detection](https://arxiv.org/abs/2106.00666) by Yuxin Fang, Bencheng Liao, Xinggang Wang, Jiemin Fang, Jiyang Qi, Rui Wu, Jianwei Niu, Wenyu Liu.
+1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
+
+
+### 지원 프레임워크[[supported-framework]]
+
+아래 표는 라이브러리 속 각 모델의 지원 현황을 나타냅니다. 토큰화를 파이썬 (별칭 "slow") 또는 🤗 Tokenizers (별칭 "fast") 라이브러리로 하는지; (Flax를 통한) Jax, PyTorch, TensorFlow 중 어떤 프레임워크를 지원하는지 표시되어 있습니다.
+
+
+
+| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:---------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBird-Pegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BLOOM | ❌ | ✅ | ✅ | ❌ | ❌ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| CANINE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CLIPSeg | ❌ | ❌ | ✅ | ❌ | ❌ |
+| CodeGen | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Conditional DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNeXT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| CvT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecVision | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Deformable DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DonutSwin | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ERNIE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ESM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FLAVA | ❌ | ❌ | ✅ | ❌ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT NeoX | ❌ | ✅ | ✅ | ❌ | ❌ |
+| GPT NeoX Japanese | ✅ | ❌ | ✅ | ❌ | ❌ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| GroupViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Jukebox | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LayoutLMv3 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LeViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LiLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LongT5 | ❌ | ❌ | ✅ | ❌ | ✅ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M-CTC-T | ❌ | ❌ | ✅ | ❌ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MarkupLM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Megatron-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MobileViT | ❌ | ❌ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MVP | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Nezha | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Nyströmformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| OPT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| OWL-ViT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| PEGASUS-X | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| REALM | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoCBert | ✅ | ❌ | ✅ | ❌ | ❌ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| SegFormer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Swin Transformer | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Swin Transformer V2 | ❌ | ❌ | ✅ | ❌ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Table Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Time Series Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Trajectory Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VideoMAE | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| VisualBERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| ViTMSN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| Wav2Vec2-Conformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Whisper | ✅ | ❌ | ✅ | ✅ | ❌ |
+| X-CLIP | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOLOS | ❌ | ❌ | ✅ | ❌ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/installation.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/installation.md
new file mode 100644
index 0000000000000000000000000000000000000000..a744db40d291236a10b6b93c06d99c0b31a0a33d
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/installation.md
@@ -0,0 +1,245 @@
+
+
+# 설치방법[[installation]]
+
+🤗 Transformers를 사용 중인 딥러닝 라이브러리에 맞춰 설치하고, 캐시를 구성하거나 선택적으로 오프라인에서도 실행할 수 있도록 🤗 Transformers를 설정하는 방법을 배우겠습니다.
+
+🤗 Transformers는 Python 3.6+, PyTorch 1.1.0+, TensorFlow 2.0+ 및 Flax에서 테스트되었습니다. 딥러닝 라이브러리를 설치하려면 아래 링크된 저마다의 공식 사이트를 참고해주세요.
+
+* [PyTorch](https://pytorch.org/get-started/locally/) 설치하기
+* [TensorFlow 2.0](https://www.tensorflow.org/install/pip) 설치하기
+* [Flax](https://flax.readthedocs.io/en/latest/) 설치하기
+
+## pip으로 설치하기[[install-with-pip]]
+
+🤗 Transformers를 [가상 환경](https://docs.python.org/3/library/venv.html)에 설치하는 것을 추천드립니다. Python 가상 환경에 익숙하지 않다면, 이 [가이드](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/)를 참고하세요. 가상 환경을 사용하면 서로 다른 프로젝트들을 보다 쉽게 관리할 수 있고, 의존성 간의 호환성 문제를 방지할 수 있습니다.
+
+먼저 프로젝트 디렉토리에서 가상 환경을 만들어 줍니다.
+
+```bash
+python -m venv .env
+```
+
+가상 환경을 활성화해주세요. Linux나 MacOS의 경우:
+
+```bash
+source .env/bin/activate
+```
+Windows의 경우:
+
+```bash
+.env/Scripts/activate
+```
+
+이제 🤗 Transformers를 설치할 준비가 되었습니다. 다음 명령을 입력해주세요.
+
+```bash
+pip install transformers
+```
+
+CPU만 써도 된다면, 🤗 Transformers와 딥러닝 라이브러리를 단 1줄로 설치할 수 있습니다. 예를 들어 🤗 Transformers와 PyTorch의 경우:
+
+```bash
+pip install transformers[torch]
+```
+
+🤗 Transformers와 TensorFlow 2.0의 경우:
+
+```bash
+pip install transformers[tf-cpu]
+```
+
+🤗 Transformers와 Flax의 경우:
+
+```bash
+pip install transformers[flax]
+```
+
+마지막으로 🤗 Transformers가 제대로 설치되었는지 확인할 차례입니다. 사전훈련된 모델을 다운로드하는 코드입니다.
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('we love you'))"
+```
+
+라벨과 점수가 출력되면 잘 설치된 것입니다.
+
+```bash
+[{'label': 'POSITIVE', 'score': 0.9998704791069031}]
+```
+
+## 소스에서 설치하기[[install-from-source]]
+
+🤗 Transformers를 소스에서 설치하려면 아래 명령을 실행하세요.
+
+```bash
+pip install git+https://github.com/huggingface/transformers
+```
+
+위 명령은 최신이지만 (안정적인) `stable` 버전이 아닌 실험성이 짙은 `main` 버전을 설치합니다. `main` 버전은 개발 현황과 발맞추는데 유용합니다. 예시로 마지막 공식 릴리스 이후 발견된 버그가 패치되었지만, 새 릴리스로 아직 롤아웃되지는 않은 경우를 들 수 있습니다. 바꿔 말하면 `main` 버전이 안정성과는 거리가 있다는 뜻이기도 합니다. 저희는 `main` 버전을 사용하는데 문제가 없도록 노력하고 있으며, 대부분의 문제는 대개 몇 시간이나 하루 안에 해결됩니다. 만약 문제가 발생하면 [이슈](https://github.com/huggingface/transformers/issues)를 열어주시면 더 빨리 해결할 수 있습니다!
+
+전과 마찬가지로 🤗 Transformers가 제대로 설치되었는지 확인할 차례입니다.
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('I love you'))"
+```
+
+## 수정 가능한 설치[[editable-install]]
+
+수정 가능한 설치가 필요한 경우는 다음과 같습니다.
+
+* `main` 버전의 소스 코드를 사용하기 위해
+* 🤗 Transformers에 기여하고 싶어서 코드의 변경 사항을 테스트하기 위해
+
+리포지터리를 복제하고 🤗 Transformers를 설치하려면 다음 명령을 입력해주세요.
+
+```bash
+git clone https://github.com/huggingface/transformers.git
+cd transformers
+pip install -e .
+```
+
+위 명령은 리포지터리를 복제한 위치의 폴더와 Python 라이브러리의 경로를 연결시킵니다. Python이 일반 라이브러리 경로 외에 복제한 폴더 내부를 확인할 것입니다. 예를 들어 Python 패키지가 일반적으로 `~/anaconda3/envs/main/lib/python3.7/site-packages/`에 설치되어 있는데, 명령을 받은 Python이 이제 복제한 폴더인 `~/transformers/`도 검색하게 됩니다.
+
+
 +
+ BLIP-2 구조. 원본 논문 에서 발췌.
+
+이 모델은 [nielsr](https://huggingface.co/nielsr)가 기여했습니다. 원본 코드는 [여기](https://github.com/salesforce/LAVIS/tree/5ee63d688ba4cebff63acee04adaef2dee9af207)에서 확인할 수 있습니다.
+
+## 사용 팁[[usage-tips]]
+
+- BLIP-2는 이미지와 조건에 따라 텍스트 프롬프트를 입력받아 조건부 텍스트를 생성합니다. 추론 시 [`generate`] 메소드를 사용하는 것이 권장됩니다.
+- [`Blip2Processor`]를 사용하여 모델에 이미지를 준비하고, 예측된 토큰 ID를 텍스트로 디코딩할 수 있습니다.
+
+## 자료[[resources]]
+
+BLIP-2를 시작하는 데 도움이 되는 공식 Hugging Face 및 커뮤니티(🌎 표시) 자료 목록입니다.
+
+- 이미지 캡셔닝, 시각 질문 응답(VQA), 채팅과 같은 대화형 작업을 위한 BLIP-2 데모 노트북은 [여기](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/BLIP-2)에서 찾을 수 있습니다.
+
+리소스를 제출하여 여기에 포함하고 싶다면 언제든지 풀 리퀘스트를 열어주세요! 리소스는 기존 리소스를 복제하지 않고 새로운 내용이어야 합니다.
+
+## Blip2Config[[transformers.Blip2Config]]
+
+[[autodoc]] Blip2Config
+ - from_vision_qformer_text_configs
+
+## Blip2VisionConfig[[transformers.Blip2VisionConfig]]
+
+[[autodoc]] Blip2VisionConfig
+
+## Blip2QFormerConfig[[transformers.Blip2QFormerConfig]]
+
+[[autodoc]] Blip2QFormerConfig
+
+## Blip2Processor[[transformers.Blip2Processor]]
+
+[[autodoc]] Blip2Processor
+
+## Blip2VisionModel[[transformers.Blip2VisionModel]]
+
+[[autodoc]] Blip2VisionModel
+ - forward
+
+## Blip2QFormerModel[[transformers.Blip2QFormerModel]]
+
+[[autodoc]] Blip2QFormerModel
+ - forward
+
+## Blip2Model[[transformers.Blip2Model]]
+
+[[autodoc]] Blip2Model
+ - forward
+ - get_text_features
+ - get_image_features
+ - get_qformer_features
+
+## Blip2ForConditionalGeneration[[transformers.Blip2ForConditionalGeneration]]
+
+[[autodoc]] Blip2ForConditionalGeneration
+ - forward
+ - generate
+
+## Blip2ForImageTextRetrieval[[transformers.Blip2ForImageTextRetrieval]]
+
+[[autodoc]] Blip2ForImageTextRetrieval
+ - forward
+
+## Blip2TextModelWithProjection[[transformers.Blip2TextModelWithProjection]]
+
+[[autodoc]] Blip2TextModelWithProjection
+
+## Blip2VisionModelWithProjection[[transformers.Blip2VisionModelWithProjection]]
+
+[[autodoc]] Blip2VisionModelWithProjection
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/blip.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/blip.md
new file mode 100644
index 0000000000000000000000000000000000000000..27e085315b891130598a49e4de909ccc28ecc8d5
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/blip.md
@@ -0,0 +1,136 @@
+
+
+# BLIP[[blip]]
+
+## 개요[[overview]]
+
+BLIP 모델은 Junnan Li, Dongxu Li, Caiming Xiong, Steven Hoi의 [BLIP: Bootstrapping Language-Image Pre-training for Unified Vision-Language Understanding and Generation](https://arxiv.org/abs/2201.12086) 논문에서 제안되었습니다.
+
+BLIP은 여러 멀티모달 작업을 수행할 수 있는 모델입니다:
+
+- 시각 질문 응답 (Visual Question Answering, VQA)
+- 이미지-텍스트 검색 (이미지-텍스트 매칭)
+- 이미지 캡셔닝
+
+논문의 초록은 다음과 같습니다:
+
+*비전-언어 사전 학습(Vision-Language Pre-training, VLP)은 다양한 비전-언어 작업의 성능을 크게 향상시켰습니다. 하지만, 대부분의 기존 사전 학습 모델들은 이해 기반 작업이나 생성 기반 작업 중 하나에서만 뛰어난 성능을 발휘합니다. 또한 성능 향상은 주로 웹에서 수집한 노이즈가 많은 이미지-텍스트 쌍으로 데이터셋의 규모를 키우는 방식으로 이루어졌는데, 이는 최적의 지도 학습 방식이라고 보기 어렵습니다. 본 논문에서는 BLIP이라는 새로운 VLP 프레임워크를 제안합니다. 이 프레임워크는 비전-언어 이해 및 생성 작업 모두에 유연하게 적용될 수 있습니다. BLIP는 캡셔너가 합성 캡션을 생성하고 필터가 노이즈 캡션을 제거하는 부트스트래핑 방법을 통해 웹 데이터의 노이즈를 효과적으로 활용합니다. 우리는 이미지-텍스트 검색(Recall@1에서 +2.7%), 이미지 캡셔닝(CIDEr에서 +2.8%), 그리고 VQA(VQA 점수에서 +1.6%)와 같은 다양한 비전-언어 작업에서 최신 성과를 달성했습니다. 또한 BLIP은 제로샷 방식으로 비디오-언어 작업에 직접 전이될 때도 강력한 일반화 능력을 보여줍니다. 이 논문의 코드, 모델, 데이터셋은 공개되었습니다.*
+
+
+
+이 모델은 [ybelkada](https://huggingface.co/ybelkada)가 기여했습니다.
+원본 코드는 [여기](https://github.com/salesforce/BLIP)에서 찾을 수 있습니다.
+
+## 자료[[resources]]
+
+- [Jupyter notebook](https://github.com/huggingface/notebooks/blob/main/examples/image_captioning_blip.ipynb): 사용자 정의 데이터셋에서 BLIP를 이미지 캡셔닝으로 미세 조정하는 방법
+
+## BlipConfig[[transformers.BlipConfig]]
+
+[[autodoc]] BlipConfig
+ - from_text_vision_configs
+
+## BlipTextConfig[[transformers.BlipTextConfig]]
+
+[[autodoc]] BlipTextConfig
+
+## BlipVisionConfig[[transformers.BlipVisionConfig]]
+
+[[autodoc]] BlipVisionConfig
+
+## BlipProcessor[[transformers.BlipProcessor]]
+
+[[autodoc]] BlipProcessor
+
+## BlipImageProcessor[[transformers.BlipImageProcessor]]
+
+[[autodoc]] BlipImageProcessor
+ - preprocess
+
+
 +
+Chameleon은 이미지를 이산적인 토큰으로 변환하기 위해 벡터 양자화 모듈을 통합합니다. 이는 자기회귀 transformer를 사용한 이미지 생성을 가능하게 합니다. 원본 논문에서 가져왔습니다.
+
+이 모델은 [joaogante](https://huggingface.co/joaogante)와 [RaushanTurganbay](https://huggingface.co/RaushanTurganbay)가 기여했습니다. 원본 코드는 [여기](https://github.com/facebookresearch/chameleon)에서 찾을 수 있습니다.
+
+## 사용 팁 [[usage-tips]]
+
+- 더 정확한 결과를 위해, 배치 생성 시 `padding_side="left"`를 사용하는 것을 권장합니다. 생성하기 전에 `processor.tokenizer.padding_side = "left"`로 설정하십시오.
+
+- Chameleon은 안전성 정렬을 위해 튜닝되었음을 유의하십시오. 모델이 응답을 거부하는 경우, 열린 질문보다는 더 구체적으로 질문을 해보세요.
+
+- Chameleon은 채팅 형식으로 생성하므로, 생성된 텍스트는 항상 "assistant's turn"으로 표시됩니다. 프로세서를 호출할 때 `return_for_text_completion=True`를 전달하여 텍스트 완성 생성을 활성화할 수 있습니다.
+
+> [!NOTE]
+> Transformers에서의 Chameleon 구현은 이미지 임베딩을 병합할 위치를 나타내기 위해 특별한 이미지 토큰을 사용합니다. 특별한 이미지 토큰을 위해 새로운 토큰을 추가하지 않고 예약된 토큰 중 하나인 `
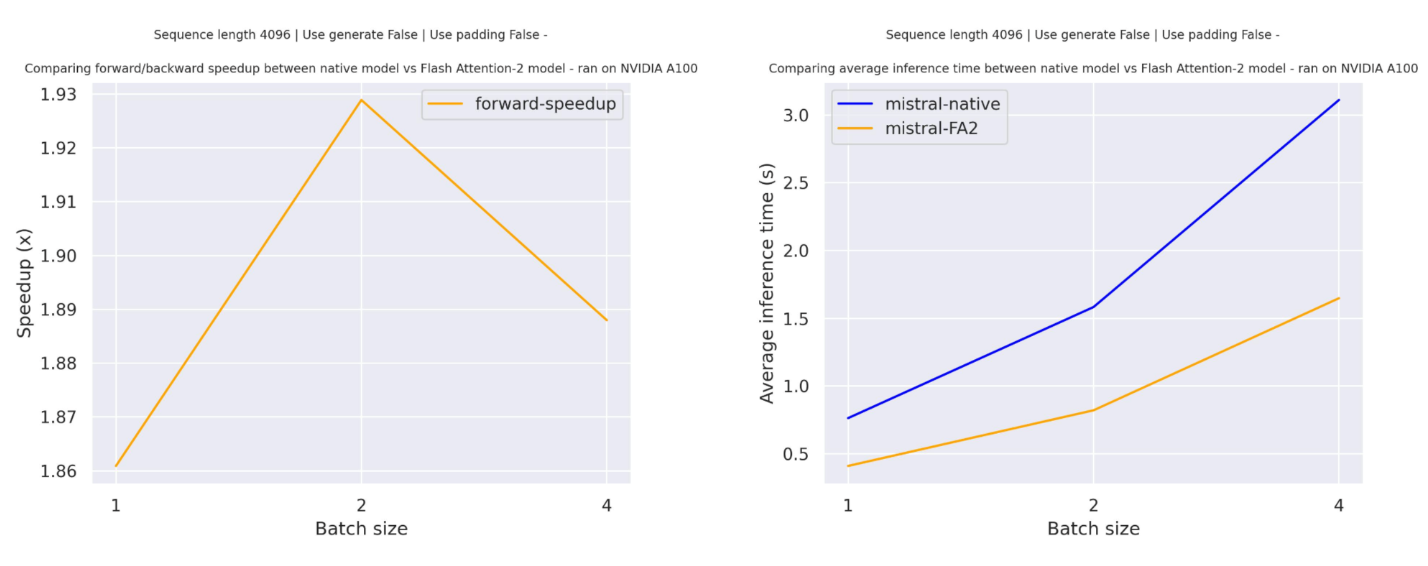 +
 +
+ PaliGemma 아키텍처 블로그 포스트.
+
+이 모델은 [Molbap](https://huggingface.co/Molbap)에 의해 기여 되었습니다.
+
+## 사용 팁[[usage-tips]]
+
+PaliGemma의 추론은 다음처럼 수행됩니다:
+
+```python
+from transformers import AutoProcessor, PaliGemmaForConditionalGeneration
+
+model_id = "google/paligemma-3b-mix-224"
+model = PaliGemmaForConditionalGeneration.from_pretrained(model_id)
+processor = AutoProcessor.from_pretrained(model_id)
+
+prompt = "What is on the flower?"
+image_file = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg?download=true"
+raw_image = Image.open(requests.get(image_file, stream=True).raw)
+inputs = processor(raw_image, prompt, return_tensors="pt")
+output = model.generate(**inputs, max_new_tokens=20)
+
+print(processor.decode(output[0], skip_special_tokens=True)[len(prompt):])
+```
+
+- PaliGemma는 대화용으로 설계되지 않았으며, 특정 사용 사례에 대해 미세 조정할 때 가장 잘 작동합니다. PaliGemma를 미세 조정할 수 있는 몇 가지 하위 작업에는 이미지 캡셔닝, 시각적 질문 답변(VQA), 오브젝트 디텍션, 참조 표현 분할 및 문서 이해가 포함됩니다.
+- 모델에 필요한 이미지, 텍스트 및 선택적 레이블을 준비하는데 `PaliGemmaProcessor`를 사용할 수 있습니다. PaliGemma 모델을 미세 조정할 때는, 프로세서에 `suffix`인자를 전달하여 다음 처럼 모델의 `labels`를 생성할 수 있습니다:
+
+```python
+prompt = "What is on the flower?"
+answer = "a bee"
+inputs = processor(images=raw_image, text=prompt, suffix=answer, return_tensors="pt")
+```
+
+## 자료[[resources]]
+
+PaliGemma를 시작하는 데 도움이 되는 Hugging Face와 community 자료 목록(🌎로 표시됨) 입니다.여기에 포함될 자료를 제출하고 싶으시다면 PR(Pull Request)를 열어주세요. 리뷰 해드리겠습니다! 자료는 기존 자료를 복제하는 대신 새로운 내용을 담고 있어야 합니다.
+
+- PaliGemma의 모든 기능을 소개하는 블로그 포스트는 [이곳](https://huggingface.co/blog/paligemma)에서 찾을 수 있습니다. 🌎
+- Trainer API를 사용하여 VQA(Visual Question Answering)를 위해 PaliGemma를 미세 조정하는 방법과 추론에 대한 데모 노트북은 [이곳](https://github.com/huggingface/notebooks/tree/main/examples/paligemma)에서 찾을 수 있습니다. 🌎
+- 사용자 정의 데이터셋(영수증 이미지 -> JSON)에 대해 PaliGemma를 미세 조정하는 방법과 추론에 대한 데모 노트북은 [이곳](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/PaliGemma)에서 찾을 수 있습니다. 🌎
+
+## PaliGemmaConfig[[transformers.PaliGemmaConfig]]
+
+[[autodoc]] PaliGemmaConfig
+
+## PaliGemmaProcessor[[transformers.PaliGemmaProcessor]]
+
+[[autodoc]] PaliGemmaProcessor
+
+## PaliGemmaForConditionalGeneration[[transformers.PaliGemmaForConditionalGeneration]]
+
+[[autodoc]] PaliGemmaForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/patchtsmixer.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/patchtsmixer.md
new file mode 100644
index 0000000000000000000000000000000000000000..e1463eb85de3e5aca2623fe038da4b249f9c629c
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/patchtsmixer.md
@@ -0,0 +1,95 @@
+
+
+# PatchTSMixer[[patchtsmixer]]
+
+## 개요[[overview]]
+
+PatchTSMixer 모델은 Vijay Ekambaram, Arindam Jati, Nam Nguyen, Phanwadee Sinthong, Jayant Kalagnanam이 제안한 [TSMixer: 다변량 시계열 예측을 위한 경량 MLP-Mixer 모델](https://arxiv.org/pdf/2306.09364.pdf)이라는 논문에서 소개되었습니다.
+
+
+PatchTSMixer는 MLP-Mixer 아키텍처를 기반으로 한 경량 시계열 모델링 접근법입니다. 허깅페이스 구현에서는 PatchTSMixer의 기능을 제공하여 패치, 채널, 숨겨진 특성 간의 경량 혼합을 쉽게 수행하여 효과적인 다변량 시계열 모델링을 가능하게 합니다. 또한 간단한 게이트 어텐션부터 사용자 정의된 더 복잡한 셀프 어텐션 블록까지 다양한 어텐션 메커니즘을 지원합니다. 이 모델은 사전 훈련될 수 있으며 이후 예측, 분류, 회귀와 같은 다양한 다운스트림 작업에 사용될 수 있습니다.
+
+
+해당 논문의 초록입니다:
+
+*TSMixer는 패치 처리된 시계열의 다변량 예측 및 표현 학습을 위해 설계된 다층 퍼셉트론(MLP) 모듈로만 구성된 경량 신경망 아키텍처입니다. 우리의 모델은 컴퓨터 비전 분야에서 MLP-Mixer 모델의 성공에서 영감을 받았습니다. 우리는 Vision MLP-Mixer를 시계열에 적용하는 데 따르는 과제를 보여주고, 정확도를 향상시키기 위해 경험적으로 검증된 구성 요소들을 도입합니다. 여기에는 계층 구조 및 채널 상관관계와 같은 시계열 특성을 명시적으로 모델링하기 위해 MLP-Mixer 백본에 온라인 조정 헤드를 부착하는 새로운 설계 패러다임이 포함됩니다. 또한 기존 패치 채널 혼합 방법의 일반적인 문제인 노이즈가 있는 채널 상호작용을 효과적으로 처리하고 다양한 데이터셋에 걸쳐 일반화하기 위한 하이브리드 채널 모델링 접근법을 제안합니다. 추가로, 중요한 특성을 우선시하기 위해 백본에 간단한 게이트 주의 메커니즘을 도입합니다. 이러한 경량 구성 요소들을 통합함으로써, 우리는 단순한 MLP 구조의 학습 능력을 크게 향상시켜 최소한의 컴퓨팅 사용으로 복잡한 트랜스포머 모델들을 능가하는 성능을 달성합니다. 더욱이, TSMixer의 모듈식 설계는 감독 학습과 마스크 자기 감독 학습 방법 모두와 호환되어 시계열 기초 모델의 유망한 구성 요소가 됩니다. TSMixer는 예측 작업에서 최첨단 MLP 및 트랜스포머 모델들을 상당한 차이(8-60%)로 능가합니다. 또한 최신의 강력한 Patch-Transformer 모델 벤치마크들을 메모리와 실행 시간을 크게 줄이면서(2-3배) 성능 면에서도 앞섭니다(1-2%).*
+
+이 모델은 [ajati](https://huggingface.co/ajati), [vijaye12](https://huggingface.co/vijaye12),
+[gsinthong](https://huggingface.co/gsinthong), [namctin](https://huggingface.co/namctin),
+[wmgifford](https://huggingface.co/wmgifford), [kashif](https://huggingface.co/kashif)가 기여했습니다.
+
+## 사용 예[[usage-example]]
+
+아래의 코드 스니펫은 PatchTSMixer 모델을 무작위로 초기화하는 방법을 보여줍니다.
+PatchTSMixer 모델은 [Trainer API](../trainer.md)와 호환됩니다.
+
+```python
+
+from transformers import PatchTSMixerConfig, PatchTSMixerForPrediction
+from transformers import Trainer, TrainingArguments,
+
+
+config = PatchTSMixerConfig(context_length = 512, prediction_length = 96)
+model = PatchTSMixerForPrediction(config)
+trainer = Trainer(model=model, args=training_args,
+ train_dataset=train_dataset,
+ eval_dataset=valid_dataset)
+trainer.train()
+results = trainer.evaluate(test_dataset)
+```
+
+## 사용 팁[[usage-tips]]
+
+이 모델은 시계열 분류와 시계열 회귀에도 사용될 수 있습니다. 각각[`PatchTSMixerForTimeSeriesClassification`]와 [`PatchTSMixerForRegression`] 클래스를 참조하세요.
+
+## 자료[[resources]]
+
+- PatchTSMixer를 자세히 설명하는 블로그 포스트는 여기에서 찾을 수 있습니다 [이곳](https://huggingface.co/blog/patchtsmixer). 이 블로그는 Google Colab에서도 열어볼 수 있습니다.
+
+## PatchTSMixerConfig[[transformers.PatchTSMixerConfig]]
+
+[[autodoc]] PatchTSMixerConfig
+
+
+## PatchTSMixerModel[[transformers.PatchTSMixerModel]]
+
+[[autodoc]] PatchTSMixerModel
+ - forward
+
+
+## PatchTSMixerForPrediction[[transformers.PatchTSMixerForPrediction]]
+
+[[autodoc]] PatchTSMixerForPrediction
+ - forward
+
+
+## PatchTSMixerForTimeSeriesClassification[[transformers.PatchTSMixerForTimeSeriesClassification]]
+
+[[autodoc]] PatchTSMixerForTimeSeriesClassification
+ - forward
+
+
+## PatchTSMixerForPretraining[[transformers.PatchTSMixerForPretraining]]
+
+[[autodoc]] PatchTSMixerForPretraining
+ - forward
+
+
+## PatchTSMixerForRegression[[transformers.PatchTSMixerForRegression]]
+
+[[autodoc]] PatchTSMixerForRegression
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/patchtst.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/patchtst.md
new file mode 100644
index 0000000000000000000000000000000000000000..fc9b0eb51e4a427b26f832a30e8d5c007e9a9bb1
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/patchtst.md
@@ -0,0 +1,76 @@
+
+
+# PatchTST[[patchtst]]
+
+## 개요[[overview]]
+
+The PatchTST 모델은 Yuqi Nie, Nam H. Nguyen, Phanwadee Sinthong, Jayant Kalagnanam이 제안한 [시계열 하나가 64개의 단어만큼 가치있다: 트랜스포머를 이용한 장기예측](https://arxiv.org/abs/2211.14730)라는 논문에서 소개되었습니다.
+
+이 모델은 고수준에서 시계열을 주어진 크기의 패치로 벡터화하고, 결과로 나온 벡터 시퀀스를 트랜스포머를 통해 인코딩한 다음 적절한 헤드를 통해 예측 길이의 예측을 출력합니다. 모델은 다음 그림과 같이 도식화됩니다:
+
+
+
+해당 논문의 초록입니다:
+
+*우리는 다변량 시계열 예측과 자기 감독 표현 학습을 위한 효율적인 트랜스포머 기반 모델 설계를 제안합니다. 이는 두 가지 주요 구성 요소를 기반으로 합니다:
+
+(i) 시계열을 하위 시리즈 수준의 패치로 분할하여 트랜스포머의 입력 토큰으로 사용
+(ii) 각 채널이 모든 시리즈에 걸쳐 동일한 임베딩과 트랜스포머 가중치를 공유하는 단일 단변량 시계열을 포함하는 채널 독립성. 패칭 설계는 자연스럽게 세 가지 이점을 가집니다:
+ - 지역적 의미 정보가 임베딩에 유지됩니다;
+ - 동일한 룩백 윈도우에 대해 어텐션 맵의 계산과 메모리 사용량이 제곱으로 감소합니다
+ - 모델이 더 긴 과거를 참조할 수 있습니다.
+ 우리의 채널 독립적 패치 시계열 트랜스포머(PatchTST)는 최신 트랜스포머 기반 모델들과 비교했을 때 장기 예측 정확도를 크게 향상시킬 수 있습니다. 또한 모델을 자기지도 사전 훈련 작업에 적용하여, 대규모 데이터셋에 대한 지도 학습을 능가하는 아주 뛰어난 미세 조정 성능을 달성했습니다. 한 데이터셋에서 마스크된 사전 훈련 표현을 다른 데이터셋으로 전이하는 것도 최고 수준의 예측 정확도(SOTA)를 산출했습니다.*
+
+이 모델은 [namctin](https://huggingface.co/namctin), [gsinthong](https://huggingface.co/gsinthong), [diepi](https://huggingface.co/diepi), [vijaye12](https://huggingface.co/vijaye12), [wmgifford](https://huggingface.co/wmgifford), [kashif](https://huggingface.co/kashif)에 의해 기여 되었습니다. 원본코드는 [이곳](https://github.com/yuqinie98/PatchTST)에서 확인할 수 있습니다.
+
+## 사용 팁[[usage-tips]]
+
+이 모델은 시계열 분류와 시계열 회귀에도 사용될 수 있습니다. 각각 [`PatchTSTForClassification`]와 [`PatchTSTForRegression`] 클래스를 참조하세요.
+
+## 자료[[resources]]
+
+- PatchTST를 자세히 설명하는 블로그 포스트는 [이곳](https://huggingface.co/blog/patchtst)에서 찾을 수 있습니다.
+이 블로그는 Google Colab에서도 열어볼 수 있습니다.
+
+## PatchTSTConfig[[transformers.PatchTSTConfig]]
+
+[[autodoc]] PatchTSTConfig
+
+## PatchTSTModel[[transformers.PatchTSTModel]]
+
+[[autodoc]] PatchTSTModel
+ - forward
+
+## PatchTSTForPrediction[[transformers.PatchTSTForPrediction]]
+
+[[autodoc]] PatchTSTForPrediction
+ - forward
+
+## PatchTSTForClassification[[transformers.PatchTSTForClassification]]
+
+[[autodoc]] PatchTSTForClassification
+ - forward
+
+## PatchTSTForPretraining[[transformers.PatchTSTForPretraining]]
+
+[[autodoc]] PatchTSTForPretraining
+ - forward
+
+## PatchTSTForRegression[[transformers.PatchTSTForRegression]]
+
+[[autodoc]] PatchTSTForRegression
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/rag.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/rag.md
new file mode 100644
index 0000000000000000000000000000000000000000..0ae88cc7ac5e3e08fc85a3619fb59aaef54a86a1
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/rag.md
@@ -0,0 +1,100 @@
+
+
+# RAG(검색 증강 생성) [[rag]]
+
+
 +
+
 +
+ Swin Transformer 아키텍처. 원본 논문에서 발췌.
+
+이 모델은 [novice03](https://huggingface.co/novice03)이 기여하였습니다. Tensorflow 버전은 [amyeroberts](https://huggingface.co/amyeroberts)가 기여했습니다. 원본 코드는 [여기](https://github.com/microsoft/Swin-Transformer)에서 확인할 수 있습니다.
+
+## 사용 팁 [[usage-tips]]
+
+- Swin은 입력의 높이와 너비가 `32`로 나누어질 수 있으면 어떤 크기든 지원할 수 있도록 패딩을 추가합니다.
+- Swin은 *백본*으로 사용할 수 있습니다. `output_hidden_states = True`로 설정하면, `hidden_states`와 `reshaped_hidden_states`를 모두 출력합니다. `reshaped_hidden_states`는 `(batch, num_channels, height, width)` 형식을 가지며, 이는 `(batch_size, sequence_length, num_channels)` 형식과 다릅니다.
+
+## 리소스 [[resources]]
+
+Swin Transformer의 사용을 도울 수 있는 Hugging Face 및 커뮤니티(🌎로 표시)의 공식 자료 목록입니다.
+
+
 +
+ Swin2SR 아키텍처. 원본 논문에서 발췌.
+
+이 모델은 [nielsr](https://huggingface.co/nielsr)가 기여하였습니다.
+원본 코드는 [여기](https://github.com/mv-lab/swin2sr)에서 확인할 수 있습니다.
+
+## 리소스 [[resources]]
+
+Swin2SR demo notebook은 [여기](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Swin2SR)에서 확인할 수 있습니다.
+
+SwinSR을 활용한 image super-resolution demo space는 [여기](https://huggingface.co/spaces/jjourney1125/swin2sr)에서 확인할 수 있습니다.
+
+## Swin2SRImageProcessor [[transformers.Swin2SRImageProcessor]]
+
+[[autodoc]] Swin2SRImageProcessor
+ - preprocess
+
+## Swin2SRConfig [[transformers.Swin2SRConfig]]
+
+[[autodoc]] Swin2SRConfig
+
+## Swin2SRModel [[transformers.Swin2SRModel]]
+
+[[autodoc]] Swin2SRModel
+ - forward
+
+## Swin2SRForImageSuperResolution [[transformers.Swin2SRForImageSuperResolution]]
+
+[[autodoc]] Swin2SRForImageSuperResolution
+ - forward
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/swinv2.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/swinv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..3bc420a292ad7bfd80791aafa6f4ecb40bdd4242
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/model_doc/swinv2.md
@@ -0,0 +1,63 @@
+
+
+# Swin Transformer V2 [[swin-transformer-v2]]
+
+## 개요 [[overview]]
+
+Swin Transformer V2는 Ze Liu, Han Hu, Yutong Lin, Zhuliang Yao, Zhenda Xie, Yixuan Wei, Jia Ning, Yue Cao, Zheng Zhang, Li Dong, Furu Wei, Baining Guo가 제안한 논문 [Swin Transformer V2: Scaling Up Capacity and Resolution](https://arxiv.org/abs/2111.09883)에서 소개되었습니다.
+
+논문의 초록은 다음과 같습니다:
+
+*대규모 NLP 모델들은 언어 작업에서의 성능을 크게 향상하며, 성능이 포화하는 징후를 보이지 않습니다. 또한, 사람과 유사한 few-shot 학습 능력을 보여줍니다. 이 논문은 대규모 모델을 컴퓨터 비전 분야에서 탐구하고자 합니다. 대형 비전 모델을 훈련하고 적용하는 데 있어 세 가지 주요 문제를 다룹니다: 훈련 불안정성, 사전 학습과 파인튜닝 간의 해상도 차이, 그리고 레이블이 달린 데이터에 대한 높은 요구입니다. 세 가지 주요 기법을 제안합니다: 1) 훈련 안정성을 개선하기 위한 residual-post-norm 방법과 cosine attention의 결합; 2) 저해상도 이미지로 사전 학습된 모델을 고해상도 입력으로 전이할 수 있는 log-spaced continuous position bias 방법; 3) 레이블이 달린 방대한 이미지의 필요성을 줄이기 위한 self-supervised 사전 학습 방법인 SimMIM입니다. 이러한 기법들을 통해 30억 개의 파라미터를 가진 Swin Transformer V2 모델을 성공적으로 훈련하였으며, 이는 현재까지 가장 크고 고밀도의 비전 모델로, 최대 1,536×1,536 해상도의 이미지를 다룰 수 있습니다. 이 모델은 ImageNet-V2 이미지 분류, COCO 객체 탐지, ADE20K 의미론적 분할, Kinetics-400 비디오 행동 분류 등 네 가지 대표적인 비전 작업에서 새로운 성능 기록을 세웠습니다. 또한, 우리의 훈련은 Google의 billion-level 비전 모델과 비교해 40배 적은 레이블이 달린 데이터와 40배 적은 훈련 시간으로 이루어졌다는 점에서 훨씬 더 효율적입니다.*
+
+이 모델은 [nandwalritik](https://huggingface.co/nandwalritik)이 기여하였습니다.
+원본 코드는 [여기](https://github.com/microsoft/Swin-Transformer)에서 확인할 수 있습니다.
+
+## 리소스 [[resources]]
+
+Swin Transformer v2의 사용을 도울 수 있는 Hugging Face 및 커뮤니티(🌎로 표시)의 공식 자료 목록입니다.
+
+
+
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
+#### 에이전트 [[agents]]
+
+여기서 "에이전트"는 대규모 언어 모델이며, 특정 도구 모음에 접근할 수 있도록 프롬프트하고 있습니다.
+
+LLM은 작은 코드 샘플을 생성하는 데 상당히 능숙하므로,
+이 장점을 활용해 도구 모음을 사용하여 작업을 수행하는 작은 코드 샘플을 제공하라는 메시지를 표시합니다.
+그런 다음 에이전트에게 제공하는 작업과 제공하는 도구에 대한 설명으로 이 프롬프트가 완료됩니다.
+이렇게 하면 사용 중인 도구들의 문서에 접근할 수 있으며, 해당 도구들의 입력과 출력을 예상하고, 관련된 코드를 생성할 수 있습니다.
+
+#### 도구 [[tools]]
+
+도구는 매우 간단합니다. 이름과 설명이 있는 단일 기능으로 구성되어 있습니다.
+그런 다음 이러한 도구의 설명을 사용하여 상담원에게 프롬프트를 표시합니다.
+이 프롬프트를 통해 상담원에게 쿼리에서 요청된 작업을 수행하기 위해 도구를 활용하는 방법을 보여줍니다.
+
+에이전트가 매우 원자적인 도구를 사용하여 더 나은 코드를 작성하기 때문에 파이프라인이 아닌 완전히 새로운 도구를 사용합니다.
+파이프라인은 더 많이 리팩터링되며 종종 여러 작업을 하나로 결합합니다.
+도구는 하나의 매우 간단한 작업에만 집중하도록 되어 있습니다.
+
+#### 코드 실행?! [[code-execution]]
+
+그런 다음 이 코드는 도구와 함께 전달된 입력 세트에 대해 작은 Python 인터프리터를 사용하여 실행됩니다.
+"임의 코드 실행이라니!"이라고 비명을 지르는 소리가 들리겠지만, 그렇지 않은 이유를 설명하겠습니다.
+
+호출할 수 있는 함수는 제공한 도구와 인쇄 기능뿐이므로 이미 실행할 수 있는 기능이 제한되어 있습니다.
+Hugging Face 도구로 제한되어 있다면 안전할 것입니다.
+
+그리고 어트리뷰트 조회나 가져오기를 허용하지 않으므로
+(어차피 작은 함수 집합에 입/출력을 전달할 때는 필요하지 않아야 합니다)
+가장 명백한 공격(어차피 LLM에 출력하라는 메시지를 표시해야 합니다)은 문제가 되지 않습니다.
+매우 안전하게 하고 싶다면 추가 인수 return_code=True를 사용하여 run() 메소드를 실행하면 됩니다.
+이 경우 에이전트가 실행할 코드를 반환하고 실행할지 여부를 결정할 수 있습니다.
+
+불법적인 연산을 수행하려고 하거나 에이전트가 생성한 코드에 일반적인 파이썬 오류가 있는 경우
+실행이 중지됩니다.
+
+### 엄선된 도구 모음 [[a-curated-set-of-tools]]
+
+저희는 이러한 에이전트들의 역량을 강화할 수 있는 일련의 도구를 확인하고 있습니다.
+다음은 연동된 도구의 최신 목록입니다:
+
+- **문서 질문 답변**: 이미지 형식의 문서(예: PDF)가 주어지면 이 문서에 대한 질문에 답변합니다. ([Donut](./model_doc/donut))
+- **텍스트 질문 답변**: 긴 텍스트와 질문이 주어지면 텍스트에서 질문에 답변합니다. ([Flan-T5](./model_doc/flan-t5))
+- **무조건 이미지 캡셔닝**: 이미지에 캡션을 답니다! ([BLIP](./model_doc/blip))
+- **이미지 질문 답변**: 이미지가 주어지면 이 이미지에 대한 질문에 답변하기. ([VILT](./model_doc/vilt))
+- **이미지 분할**: 이미지와 프롬프트가 주어지면 해당 프롬프트의 분할 마스크를 출력합니다. ([CLIPSeg](./model_doc/clipseg))
+- **음성을 텍스트로 변환**: 사람이 말하는 오디오 녹음이 주어지면 음성을 텍스트로 변환합니다. ([Whisper](./model_doc/whisper))
+- **텍스트 음성 변환**: 텍스트를 음성으로 변환합니다. ([SpeechT5](./model_doc/speecht5))
+- **제로 샷(zero-shot) 텍스트 분류**: 텍스트와 레이블 목록이 주어지면 텍스트와 가장 관련 있는 레이블을 식별합니다. ([BART](./model_doc/bart))
+- **텍스트 요약**: 긴 텍스트를 한 문장 또는 몇 문장으로 요약합니다. ([BART](./model_doc/bart))
+- **번역**: 텍스트를 지정된 언어로 번역합니다. ([NLLB](./model_doc/nllb))
+
+이러한 도구는 트랜스포머에 통합되어 있으며, 예를 들어 수동으로도 사용할 수 있습니다:
+
+```py
+from transformers import load_tool
+
+tool = load_tool("text-to-speech")
+audio = tool("This is a text to speech tool")
+```
+
+### 사용자 정의 도구 [[custom-tools]]
+
+엄선된 도구 세트도 있지만, 이 구현이 제공하는 가장 큰 가치는 사용자 지정 도구를 빠르게 만들고 공유할 수 있다는 점입니다.
+
+도구의 코드를 Hugging Face Space나 모델 저장소에 푸시하면 에이전트에게 직접 도구를 활용할 수 있습니다. [`huggingface-tools` organization](https://huggingface.co/huggingface-tools)에 몇 가지 **트랜스포머에 구애받지 않는** 툴을 추가했습니다:
+
+- **텍스트 다운로더**: 웹 URL에서 텍스트를 다운로드합니다.
+- **텍스트 이미지 변환**: 프롬프트에 따라 이미지를 생성하여 안정적인 확산을 활용합니다.
+- **이미지 변환**: 초기 이미지와 프롬프트가 주어진 이미지를 수정하고, 안정적인 확산을 활용하는 지시 픽셀 2 픽셀을 활용합니다.
+- **텍스트 비디오 변환**: 프롬프트에 따라 작은 비디오를 생성하며, damo-vilab을 활용합니다.
+
+저희가 처음부터 사용하고 있는 텍스트-이미지 변환 도구는 [*huggingface-tools/text-to-image*](https://huggingface.co/spaces/huggingface-tools/text-to-image)에 있는 원격 도구입니다! 저희는 이 도구와 다른 조직에 이러한 도구를 계속 출시하여 이 구현을 더욱 강화할 것입니다.
+
+에이전트는 기본적으로 [`huggingface-tools`](https://huggingface.co/huggingface-tools)에 있는 도구에 접근할 수 있습니다.
+[다음 가이드](custom_tools)에서 도구를 작성하고 공유하는 방법과 Hub에 있는 사용자 지정 도구를 활용하는 방법에 대해 설명합니다.
+
+### 코드 생성[[code-generation]]
+
+지금까지 에이전트를 사용하여 작업을 수행하는 방법을 보여드렸습니다. 하지만 에이전트는 매우 제한된 Python 인터프리터를 사용하여 실행할 코드만 생성하고 있습니다. 다른 설정에서 생성된 코드를 사용하려는 경우 에이전트에게 도구 정의 및 정확한 가져오기와 함께 코드를 반환하라는 메시지를 표시할 수 있습니다.
+
+예를 들어 다음 명령어는
+```python
+agent.run("Draw me a picture of rivers and lakes", return_code=True)
+```
+
+다음 코드를 반환합니다.
+
+```python
+from transformers import load_tool
+
+image_generator = load_tool("huggingface-tools/text-to-image")
+
+image = image_generator(prompt="rivers and lakes")
+```
+
+이 코드는 직접 수정하고 실행할 수 있습니다.
\ No newline at end of file
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/troubleshooting.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/troubleshooting.md
new file mode 100644
index 0000000000000000000000000000000000000000..263d693c23da65f7a964ee64fdde70dff595ad2c
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/ko/troubleshooting.md
@@ -0,0 +1,198 @@
+
+
+# 문제 해결[[troubleshoot]]
+
+때때로 오류가 발생할 수 있지만, 저희가 도와드리겠습니다! 이 가이드는 현재까지 확인된 가장 일반적인 문제 몇 가지와 그것들을 해결하는 방법에 대해 다룹니다. 그러나 이 가이드는 모든 🤗 Transformers 문제를 포괄적으로 다루고 있지 않습니다. 문제 해결에 더 많은 도움을 받으려면 다음을 시도해보세요:
+
+
 +
+
+## Conteúdo
+
+A documentação é dividida em cinco partes:
+ - **INÍCIO** contém um tour rápido de instalação e instruções para te dar um empurrão inicial com os 🤗 Transformers.
+ - **TUTORIAIS** são perfeitos para começar a aprender sobre a nossa biblioteca. Essa seção irá te ajudar a desenvolver
+ habilidades básicas necessárias para usar o 🤗 Transformers.
+ - **GUIAS PRÁTICOS** irão te mostrar como alcançar um certo objetivo, como o fine-tuning de um modelo pré-treinado
+ para modelamento de idioma, ou como criar um cabeçalho personalizado para um modelo.
+ - **GUIAS CONCEITUAIS** te darão mais discussões e explicações dos conceitos fundamentais e idéias por trás dos modelos,
+ tarefas e da filosofia de design por trás do 🤗 Transformers.
+ - **API** descreve o funcionamento de cada classe e função, agrupada em:
+
+ - **CLASSES PRINCIPAIS** para as classes que expõe as APIs importantes da biblioteca.
+ - **MODELOS** para as classes e funções relacionadas à cada modelo implementado na biblioteca.
+ - **AUXILIARES INTERNOS** para as classes e funções usadas internamente.
+
+Atualmente a biblioteca contém implementações do PyTorch, TensorFlow e JAX, pesos para modelos pré-treinados e scripts de uso e conversão de utilidades para os seguintes modelos:
+
+### Modelos atuais
+
+
+
+1. **[ALBERT](model_doc/albert)** (from Google Research and the Toyota Technological Institute at Chicago) released with the paper [ALBERT: A Lite BERT for Self-supervised Learning of Language Representations](https://arxiv.org/abs/1909.11942), by Zhenzhong Lan, Mingda Chen, Sebastian Goodman, Kevin Gimpel, Piyush Sharma, Radu Soricut.
+1. **[BART](model_doc/bart)** (from Facebook) released with the paper [BART: Denoising Sequence-to-Sequence Pre-training for Natural Language Generation, Translation, and Comprehension](https://arxiv.org/abs/1910.13461) by Mike Lewis, Yinhan Liu, Naman Goyal, Marjan Ghazvininejad, Abdelrahman Mohamed, Omer Levy, Ves Stoyanov and Luke Zettlemoyer.
+1. **[BARThez](model_doc/barthez)** (from École polytechnique) released with the paper [BARThez: a Skilled Pretrained French Sequence-to-Sequence Model](https://arxiv.org/abs/2010.12321) by Moussa Kamal Eddine, Antoine J.-P. Tixier, Michalis Vazirgiannis.
+1. **[BARTpho](model_doc/bartpho)** (from VinAI Research) released with the paper [BARTpho: Pre-trained Sequence-to-Sequence Models for Vietnamese](https://arxiv.org/abs/2109.09701) by Nguyen Luong Tran, Duong Minh Le and Dat Quoc Nguyen.
+1. **[BEiT](model_doc/beit)** (from Microsoft) released with the paper [BEiT: BERT Pre-Training of Image Transformers](https://arxiv.org/abs/2106.08254) by Hangbo Bao, Li Dong, Furu Wei.
+1. **[BERT](model_doc/bert)** (from Google) released with the paper [BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding](https://arxiv.org/abs/1810.04805) by Jacob Devlin, Ming-Wei Chang, Kenton Lee and Kristina Toutanova.
+1. **[BERTweet](model_doc/bertweet)** (from VinAI Research) released with the paper [BERTweet: A pre-trained language model for English Tweets](https://aclanthology.org/2020.emnlp-demos.2/) by Dat Quoc Nguyen, Thanh Vu and Anh Tuan Nguyen.
+1. **[BERT For Sequence Generation](model_doc/bert-generation)** (from Google) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[BigBird-RoBERTa](model_doc/big_bird)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[BigBird-Pegasus](model_doc/bigbird_pegasus)** (from Google Research) released with the paper [Big Bird: Transformers for Longer Sequences](https://arxiv.org/abs/2007.14062) by Manzil Zaheer, Guru Guruganesh, Avinava Dubey, Joshua Ainslie, Chris Alberti, Santiago Ontanon, Philip Pham, Anirudh Ravula, Qifan Wang, Li Yang, Amr Ahmed.
+1. **[Blenderbot](model_doc/blenderbot)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BlenderbotSmall](model_doc/blenderbot-small)** (from Facebook) released with the paper [Recipes for building an open-domain chatbot](https://arxiv.org/abs/2004.13637) by Stephen Roller, Emily Dinan, Naman Goyal, Da Ju, Mary Williamson, Yinhan Liu, Jing Xu, Myle Ott, Kurt Shuster, Eric M. Smith, Y-Lan Boureau, Jason Weston.
+1. **[BORT](model_doc/bort)** (from Alexa) released with the paper [Optimal Subarchitecture Extraction For BERT](https://arxiv.org/abs/2010.10499) by Adrian de Wynter and Daniel J. Perry.
+1. **[ByT5](model_doc/byt5)** (from Google Research) released with the paper [ByT5: Towards a token-free future with pre-trained byte-to-byte models](https://arxiv.org/abs/2105.13626) by Linting Xue, Aditya Barua, Noah Constant, Rami Al-Rfou, Sharan Narang, Mihir Kale, Adam Roberts, Colin Raffel.
+1. **[CamemBERT](model_doc/camembert)** (from Inria/Facebook/Sorbonne) released with the paper [CamemBERT: a Tasty French Language Model](https://arxiv.org/abs/1911.03894) by Louis Martin*, Benjamin Muller*, Pedro Javier Ortiz Suárez*, Yoann Dupont, Laurent Romary, Éric Villemonte de la Clergerie, Djamé Seddah and Benoît Sagot.
+1. **[CANINE](model_doc/canine)** (from Google Research) released with the paper [CANINE: Pre-training an Efficient Tokenization-Free Encoder for Language Representation](https://arxiv.org/abs/2103.06874) by Jonathan H. Clark, Dan Garrette, Iulia Turc, John Wieting.
+1. **[ConvNeXT](model_doc/convnext)** (from Facebook AI) released with the paper [A ConvNet for the 2020s](https://arxiv.org/abs/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+1. **[ConvNeXTV2](model_doc/convnextv2)** (from Facebook AI) released with the paper [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://arxiv.org/abs/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+1. **[CLIP](model_doc/clip)** (from OpenAI) released with the paper [Learning Transferable Visual Models From Natural Language Supervision](https://arxiv.org/abs/2103.00020) by Alec Radford, Jong Wook Kim, Chris Hallacy, Aditya Ramesh, Gabriel Goh, Sandhini Agarwal, Girish Sastry, Amanda Askell, Pamela Mishkin, Jack Clark, Gretchen Krueger, Ilya Sutskever.
+1. **[ConvBERT](model_doc/convbert)** (from YituTech) released with the paper [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://arxiv.org/abs/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng Yan.
+1. **[CPM](model_doc/cpm)** (from Tsinghua University) released with the paper [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://arxiv.org/abs/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin, Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen, Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+1. **[CTRL](model_doc/ctrl)** (from Salesforce) released with the paper [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://arxiv.org/abs/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and Richard Socher.
+1. **[Data2Vec](model_doc/data2vec)** (from Facebook) released with the paper [Data2Vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://arxiv.org/abs/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu, Michael Auli.
+1. **[DeBERTa](model_doc/deberta)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[DeBERTa-v2](model_doc/deberta-v2)** (from Microsoft) released with the paper [DeBERTa: Decoding-enhanced BERT with Disentangled Attention](https://arxiv.org/abs/2006.03654) by Pengcheng He, Xiaodong Liu, Jianfeng Gao, Weizhu Chen.
+1. **[Decision Transformer](model_doc/decision_transformer)** (from Berkeley/Facebook/Google) released with the paper [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://arxiv.org/abs/2106.01345) by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+1. **[DiT](model_doc/dit)** (from Microsoft Research) released with the paper [DiT: Self-supervised Pre-training for Document Image Transformer](https://arxiv.org/abs/2203.02378) by Junlong Li, Yiheng Xu, Tengchao Lv, Lei Cui, Cha Zhang, Furu Wei.
+1. **[DeiT](model_doc/deit)** (from Facebook) released with the paper [Training data-efficient image transformers & distillation through attention](https://arxiv.org/abs/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre Sablayrolles, Hervé Jégou.
+1. **[DETR](model_doc/detr)** (from Facebook) released with the paper [End-to-End Object Detection with Transformers](https://arxiv.org/abs/2005.12872) by Nicolas Carion, Francisco Massa, Gabriel Synnaeve, Nicolas Usunier, Alexander Kirillov, Sergey Zagoruyko.
+1. **[DialoGPT](model_doc/dialogpt)** (from Microsoft Research) released with the paper [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://arxiv.org/abs/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao, Jianfeng Gao, Jingjing Liu, Bill Dolan.
+1. **[DistilBERT](model_doc/distilbert)** (from HuggingFace), released together with the paper [DistilBERT, a distilled version of BERT: smaller, faster, cheaper and lighter](https://arxiv.org/abs/1910.01108) by Victor Sanh, Lysandre Debut and Thomas Wolf. The same method has been applied to compress GPT2 into [DistilGPT2](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), RoBERTa into [DistilRoBERTa](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation), Multilingual BERT into [DistilmBERT](https://github.com/huggingface/transformers/tree/main/examples/research_projects/distillation) and a German version of DistilBERT.
+1. **[DPR](model_doc/dpr)** (from Facebook) released with the paper [Dense Passage Retrieval for Open-Domain Question Answering](https://arxiv.org/abs/2004.04906) by Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, and Wen-tau Yih.
+1. **[DPT](master/model_doc/dpt)** (from Intel Labs) released with the paper [Vision Transformers for Dense Prediction](https://arxiv.org/abs/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+1. **[EfficientNet](model_doc/efficientnet)** (from Google Research) released with the paper [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://arxiv.org/abs/1905.11946) by Mingxing Tan and Quoc V. Le.
+1. **[EncoderDecoder](model_doc/encoder-decoder)** (from Google Research) released with the paper [Leveraging Pre-trained Checkpoints for Sequence Generation Tasks](https://arxiv.org/abs/1907.12461) by Sascha Rothe, Shashi Narayan, Aliaksei Severyn.
+1. **[ELECTRA](model_doc/electra)** (from Google Research/Stanford University) released with the paper [ELECTRA: Pre-training text encoders as discriminators rather than generators](https://arxiv.org/abs/2003.10555) by Kevin Clark, Minh-Thang Luong, Quoc V. Le, Christopher D. Manning.
+1. **[FlauBERT](model_doc/flaubert)** (from CNRS) released with the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://arxiv.org/abs/1912.05372) by Hang Le, Loïc Vial, Jibril Frej, Vincent Segonne, Maximin Coavoux, Benjamin Lecouteux, Alexandre Allauzen, Benoît Crabbé, Laurent Besacier, Didier Schwab.
+1. **[FNet](model_doc/fnet)** (from Google Research) released with the paper [FNet: Mixing Tokens with Fourier Transforms](https://arxiv.org/abs/2105.03824) by James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon.
+1. **[Funnel Transformer](model_doc/funnel)** (from CMU/Google Brain) released with the paper [Funnel-Transformer: Filtering out Sequential Redundancy for Efficient Language Processing](https://arxiv.org/abs/2006.03236) by Zihang Dai, Guokun Lai, Yiming Yang, Quoc V. Le.
+1. **[GLPN](model_doc/glpn)** (from KAIST) released with the paper [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://arxiv.org/abs/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+1. **[GPT](model_doc/openai-gpt)** (from OpenAI) released with the paper [Improving Language Understanding by Generative Pre-Training](https://openai.com/research/language-unsupervised/) by Alec Radford, Karthik Narasimhan, Tim Salimans and Ilya Sutskever.
+1. **[GPT-2](model_doc/gpt2)** (from OpenAI) released with the paper [Language Models are Unsupervised Multitask Learners](https://openai.com/research/better-language-models/) by Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei and Ilya Sutskever.
+1. **[GPT-J](model_doc/gptj)** (from EleutherAI) released in the repository [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax/) by Ben Wang and Aran Komatsuzaki.
+1. **[GPT Neo](model_doc/gpt_neo)** (from EleutherAI) released in the repository [EleutherAI/gpt-neo](https://github.com/EleutherAI/gpt-neo) by Sid Black, Stella Biderman, Leo Gao, Phil Wang and Connor Leahy.
+1. **[GPTSAN-japanese](model_doc/gptsan-japanese)** released in the repository [tanreinama/GPTSAN](https://github.com/tanreinama/GPTSAN/blob/main/report/model.md) by Toshiyuki Sakamoto(tanreinama).
+1. **[Hubert](model_doc/hubert)** (from Facebook) released with the paper [HuBERT: Self-Supervised Speech Representation Learning by Masked Prediction of Hidden Units](https://arxiv.org/abs/2106.07447) by Wei-Ning Hsu, Benjamin Bolte, Yao-Hung Hubert Tsai, Kushal Lakhotia, Ruslan Salakhutdinov, Abdelrahman Mohamed.
+1. **[I-BERT](model_doc/ibert)** (from Berkeley) released with the paper [I-BERT: Integer-only BERT Quantization](https://arxiv.org/abs/2101.01321) by Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney, Kurt Keutzer.
+1. **[ImageGPT](model_doc/imagegpt)** (from OpenAI) released with the paper [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt/) by Mark Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever.
+1. **[LayoutLM](model_doc/layoutlm)** (from Microsoft Research Asia) released with the paper [LayoutLM: Pre-training of Text and Layout for Document Image Understanding](https://arxiv.org/abs/1912.13318) by Yiheng Xu, Minghao Li, Lei Cui, Shaohan Huang, Furu Wei, Ming Zhou.
+1. **[LayoutLMv2](model_doc/layoutlmv2)** (from Microsoft Research Asia) released with the paper [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://arxiv.org/abs/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou.
+1. **[LayoutXLM](model_doc/layoutxlm)** (from Microsoft Research Asia) released with the paper [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://arxiv.org/abs/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha Zhang, Furu Wei.
+1. **[LED](model_doc/led)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[Longformer](model_doc/longformer)** (from AllenAI) released with the paper [Longformer: The Long-Document Transformer](https://arxiv.org/abs/2004.05150) by Iz Beltagy, Matthew E. Peters, Arman Cohan.
+1. **[LUKE](model_doc/luke)** (from Studio Ousia) released with the paper [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://arxiv.org/abs/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda, Yuji Matsumoto.
+1. **[mLUKE](model_doc/mluke)** (from Studio Ousia) released with the paper [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://arxiv.org/abs/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka.
+1. **[LXMERT](model_doc/lxmert)** (from UNC Chapel Hill) released with the paper [LXMERT: Learning Cross-Modality Encoder Representations from Transformers for Open-Domain Question Answering](https://arxiv.org/abs/1908.07490) by Hao Tan and Mohit Bansal.
+1. **[M2M100](model_doc/m2m_100)** (from Facebook) released with the paper [Beyond English-Centric Multilingual Machine Translation](https://arxiv.org/abs/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky, Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+1. **[MarianMT](model_doc/marian)** Machine translation models trained using [OPUS](http://opus.nlpl.eu/) data by Jörg Tiedemann. The [Marian Framework](https://marian-nmt.github.io/) is being developed by the Microsoft Translator Team.
+1. **[Mask2Former](model_doc/mask2former)** (from FAIR and UIUC) released with the paper [Masked-attention Mask Transformer for Universal Image Segmentation](https://arxiv.org/abs/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar.
+1. **[MaskFormer](model_doc/maskformer)** (from Meta and UIUC) released with the paper [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://arxiv.org/abs/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov.
+1. **[MBart](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Denoising Pre-training for Neural Machine Translation](https://arxiv.org/abs/2001.08210) by Yinhan Liu, Jiatao Gu, Naman Goyal, Xian Li, Sergey Edunov, Marjan Ghazvininejad, Mike Lewis, Luke Zettlemoyer.
+1. **[MBart-50](model_doc/mbart)** (from Facebook) released with the paper [Multilingual Translation with Extensible Multilingual Pretraining and Finetuning](https://arxiv.org/abs/2008.00401) by Yuqing Tang, Chau Tran, Xian Li, Peng-Jen Chen, Naman Goyal, Vishrav Chaudhary, Jiatao Gu, Angela Fan.
+1. **[Megatron-BERT](model_doc/megatron-bert)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[Megatron-GPT2](model_doc/megatron_gpt2)** (from NVIDIA) released with the paper [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism](https://arxiv.org/abs/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley, Jared Casper and Bryan Catanzaro.
+1. **[MPNet](model_doc/mpnet)** (from Microsoft Research) released with the paper [MPNet: Masked and Permuted Pre-training for Language Understanding](https://arxiv.org/abs/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+1. **[MT5](model_doc/mt5)** (from Google AI) released with the paper [mT5: A massively multilingual pre-trained text-to-text transformer](https://arxiv.org/abs/2010.11934) by Linting Xue, Noah Constant, Adam Roberts, Mihir Kale, Rami Al-Rfou, Aditya Siddhant, Aditya Barua, Colin Raffel.
+1. **[Nyströmformer](model_doc/nystromformer)** (from the University of Wisconsin - Madison) released with the paper [Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention](https://arxiv.org/abs/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn Fung, Yin Li, Vikas Singh.
+1. **[OneFormer](model_doc/oneformer)** (from SHI Labs) released with the paper [OneFormer: One Transformer to Rule Universal Image Segmentation](https://arxiv.org/abs/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi.
+1. **[Pegasus](model_doc/pegasus)** (from Google) released with the paper [PEGASUS: Pre-training with Extracted Gap-sentences for Abstractive Summarization](https://arxiv.org/abs/1912.08777) by Jingqing Zhang, Yao Zhao, Mohammad Saleh and Peter J. Liu.
+1. **[Perceiver IO](model_doc/perceiver)** (from Deepmind) released with the paper [Perceiver IO: A General Architecture for Structured Inputs & Outputs](https://arxiv.org/abs/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch, Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M. Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+1. **[PhoBERT](model_doc/phobert)** (from VinAI Research) released with the paper [PhoBERT: Pre-trained language models for Vietnamese](https://www.aclweb.org/anthology/2020.findings-emnlp.92/) by Dat Quoc Nguyen and Anh Tuan Nguyen.
+1. **[PLBart](model_doc/plbart)** (from UCLA NLP) released with the paper [Unified Pre-training for Program Understanding and Generation](https://arxiv.org/abs/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+1. **[PoolFormer](model_doc/poolformer)** (from Sea AI Labs) released with the paper [MetaFormer is Actually What You Need for Vision](https://arxiv.org/abs/2111.11418) by Yu, Weihao and Luo, Mi and Zhou, Pan and Si, Chenyang and Zhou, Yichen and Wang, Xinchao and Feng, Jiashi and Yan, Shuicheng.
+1. **[ProphetNet](model_doc/prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[QDQBert](model_doc/qdqbert)** (from NVIDIA) released with the paper [Integer Quantization for Deep Learning Inference: Principles and Empirical Evaluation](https://arxiv.org/abs/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius Micikevicius.
+1. **[REALM](model_doc/realm.html)** (from Google Research) released with the paper [REALM: Retrieval-Augmented Language Model Pre-Training](https://arxiv.org/abs/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang.
+1. **[Reformer](model_doc/reformer)** (from Google Research) released with the paper [Reformer: The Efficient Transformer](https://arxiv.org/abs/2001.04451) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+1. **[RemBERT](model_doc/rembert)** (from Google Research) released with the paper [Rethinking embedding coupling in pre-trained language models](https://arxiv.org/abs/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, M. Johnson, Sebastian Ruder.
+1. **[RegNet](model_doc/regnet)** (from META Platforms) released with the paper [Designing Network Design Space](https://arxiv.org/abs/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+1. **[ResNet](model_doc/resnet)** (from Microsoft Research) released with the paper [Deep Residual Learning for Image Recognition](https://arxiv.org/abs/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun.
+1. **[RoBERTa](model_doc/roberta)** (from Facebook), released together with the paper [RoBERTa: A Robustly Optimized BERT Pretraining Approach](https://arxiv.org/abs/1907.11692) by Yinhan Liu, Myle Ott, Naman Goyal, Jingfei Du, Mandar Joshi, Danqi Chen, Omer Levy, Mike Lewis, Luke Zettlemoyer, Veselin Stoyanov.
+1. **[RoFormer](model_doc/roformer)** (from ZhuiyiTechnology), released together with the paper [RoFormer: Enhanced Transformer with Rotary Position Embedding](https://arxiv.org/abs/2104.09864) by Jianlin Su and Yu Lu and Shengfeng Pan and Bo Wen and Yunfeng Liu.
+1. **[SegFormer](model_doc/segformer)** (from NVIDIA) released with the paper [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://arxiv.org/abs/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping Luo.
+1. **[SEW](model_doc/sew)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SEW-D](model_doc/sew_d)** (from ASAPP) released with the paper [Performance-Efficiency Trade-offs in Unsupervised Pre-training for Speech Recognition](https://arxiv.org/abs/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+1. **[SpeechToTextTransformer](model_doc/speech_to_text)** (from Facebook), released together with the paper [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://arxiv.org/abs/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino.
+1. **[SpeechToTextTransformer2](model_doc/speech_to_text_2)** (from Facebook), released together with the paper [Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://arxiv.org/abs/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+1. **[Splinter](model_doc/splinter)** (from Tel Aviv University), released together with the paper [Few-Shot Question Answering by Pretraining Span Selection](https://arxiv.org/abs/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy.
+1. **[SqueezeBert](model_doc/squeezebert)** (from Berkeley) released with the paper [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://arxiv.org/abs/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, and Kurt W. Keutzer.
+1. **[Swin Transformer](model_doc/swin)** (from Microsoft) released with the paper [Swin Transformer: Hierarchical Vision Transformer using Shifted Windows](https://arxiv.org/abs/2103.14030) by Ze Liu, Yutong Lin, Yue Cao, Han Hu, Yixuan Wei, Zheng Zhang, Stephen Lin, Baining Guo.
+1. **[T5](model_doc/t5)** (from Google AI) released with the paper [Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer](https://arxiv.org/abs/1910.10683) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[T5v1.1](model_doc/t5v1.1)** (from Google AI) released in the repository [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511) by Colin Raffel and Noam Shazeer and Adam Roberts and Katherine Lee and Sharan Narang and Michael Matena and Yanqi Zhou and Wei Li and Peter J. Liu.
+1. **[TAPAS](model_doc/tapas)** (from Google AI) released with the paper [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://arxiv.org/abs/2004.02349) by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos.
+1. **[TAPEX](model_doc/tapex)** (from Microsoft Research) released with the paper [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://arxiv.org/abs/2107.07653) by Qian Liu, Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou.
+1. **[Transformer-XL](model_doc/transfo-xl)** (from Google/CMU) released with the paper [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://arxiv.org/abs/1901.02860) by Zihang Dai*, Zhilin Yang*, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan Salakhutdinov.
+1. **[TrOCR](model_doc/trocr)** (from Microsoft), released together with the paper [TrOCR: Transformer-based Optical Character Recognition with Pre-trained Models](https://arxiv.org/abs/2109.10282) by Minghao Li, Tengchao Lv, Lei Cui, Yijuan Lu, Dinei Florencio, Cha Zhang, Zhoujun Li, Furu Wei.
+1. **[UniSpeech](model_doc/unispeech)** (from Microsoft Research) released with the paper [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://arxiv.org/abs/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael Zeng, Xuedong Huang.
+1. **[UniSpeechSat](model_doc/unispeech-sat)** (from Microsoft Research) released with the paper [UNISPEECH-SAT: UNIVERSAL SPEECH REPRESENTATION LEARNING WITH SPEAKER AWARE PRE-TRAINING](https://arxiv.org/abs/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen, Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu.
+1. **[VAN](model_doc/van)** (from Tsinghua University and Nankai University) released with the paper [Visual Attention Network](https://arxiv.org/abs/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+1. **[ViLT](model_doc/vilt)** (from NAVER AI Lab/Kakao Enterprise/Kakao Brain) released with the paper [ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision](https://arxiv.org/abs/2102.03334) by Wonjae Kim, Bokyung Son, Ildoo Kim.
+1. **[Vision Transformer (ViT)](model_doc/vit)** (from Google AI) released with the paper [An Image is Worth 16x16 Words: Transformers for Image Recognition at Scale](https://arxiv.org/abs/2010.11929) by Alexey Dosovitskiy, Lucas Beyer, Alexander Kolesnikov, Dirk Weissenborn, Xiaohua Zhai, Thomas Unterthiner, Mostafa Dehghani, Matthias Minderer, Georg Heigold, Sylvain Gelly, Jakob Uszkoreit, Neil Houlsby.
+1. **[ViTMAE](model_doc/vit_mae)** (from Meta AI) released with the paper [Masked Autoencoders Are Scalable Vision Learners](https://arxiv.org/abs/2111.06377) by Kaiming He, Xinlei Chen, Saining Xie, Yanghao Li, Piotr Dollár, Ross Girshick.
+1. **[VisualBERT](model_doc/visual_bert)** (from UCLA NLP) released with the paper [VisualBERT: A Simple and Performant Baseline for Vision and Language](https://arxiv.org/pdf/1908.03557) by Liunian Harold Li, Mark Yatskar, Da Yin, Cho-Jui Hsieh, Kai-Wei Chang.
+1. **[WavLM](model_doc/wavlm)** (from Microsoft Research) released with the paper [WavLM: Large-Scale Self-Supervised Pre-Training for Full Stack Speech Processing](https://arxiv.org/abs/2110.13900) by Sanyuan Chen, Chengyi Wang, Zhengyang Chen, Yu Wu, Shujie Liu, Zhuo Chen, Jinyu Li, Naoyuki Kanda, Takuya Yoshioka, Xiong Xiao, Jian Wu, Long Zhou, Shuo Ren, Yanmin Qian, Yao Qian, Jian Wu, Michael Zeng, Furu Wei.
+1. **[Wav2Vec2](model_doc/wav2vec2)** (from Facebook AI) released with the paper [wav2vec 2.0: A Framework for Self-Supervised Learning of Speech Representations](https://arxiv.org/abs/2006.11477) by Alexei Baevski, Henry Zhou, Abdelrahman Mohamed, Michael Auli.
+1. **[Wav2Vec2Phoneme](model_doc/wav2vec2_phoneme)** (from Facebook AI) released with the paper [Simple and Effective Zero-shot Cross-lingual Phoneme Recognition](https://arxiv.org/abs/2109.11680) by Qiantong Xu, Alexei Baevski, Michael Auli.
+1. **[XGLM](model_doc/xglm)** (From Facebook AI) released with the paper [Few-shot Learning with Multilingual Language Models](https://arxiv.org/abs/2112.10668) by Xi Victoria Lin, Todor Mihaylov, Mikel Artetxe, Tianlu Wang, Shuohui Chen, Daniel Simig, Myle Ott, Naman Goyal, Shruti Bhosale, Jingfei Du, Ramakanth Pasunuru, Sam Shleifer, Punit Singh Koura, Vishrav Chaudhary, Brian O'Horo, Jeff Wang, Luke Zettlemoyer, Zornitsa Kozareva, Mona Diab, Veselin Stoyanov, Xian Li.
+1. **[XLM](model_doc/xlm)** (from Facebook) released together with the paper [Cross-lingual Language Model Pretraining](https://arxiv.org/abs/1901.07291) by Guillaume Lample and Alexis Conneau.
+1. **[XLM-ProphetNet](model_doc/xlm-prophetnet)** (from Microsoft Research) released with the paper [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training](https://arxiv.org/abs/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei Zhang and Ming Zhou.
+1. **[XLM-RoBERTa](model_doc/xlm-roberta)** (from Facebook AI), released together with the paper [Unsupervised Cross-lingual Representation Learning at Scale](https://arxiv.org/abs/1911.02116) by Alexis Conneau*, Kartikay Khandelwal*, Naman Goyal, Vishrav Chaudhary, Guillaume Wenzek, Francisco Guzmán, Edouard Grave, Myle Ott, Luke Zettlemoyer and Veselin Stoyanov.
+1. **[XLM-RoBERTa-XL](model_doc/xlm-roberta-xl)** (from Facebook AI), released together with the paper [Larger-Scale Transformers for Multilingual Masked Language Modeling](https://arxiv.org/abs/2105.00572) by Naman Goyal, Jingfei Du, Myle Ott, Giri Anantharaman, Alexis Conneau.
+1. **[XLNet](model_doc/xlnet)** (from Google/CMU) released with the paper [XLNet: Generalized Autoregressive Pretraining for Language Understanding](https://arxiv.org/abs/1906.08237) by Zhilin Yang*, Zihang Dai*, Yiming Yang, Jaime Carbonell, Ruslan Salakhutdinov, Quoc V. Le.
+1. **[XLSR-Wav2Vec2](model_doc/xlsr_wav2vec2)** (from Facebook AI) released with the paper [Unsupervised Cross-Lingual Representation Learning For Speech Recognition](https://arxiv.org/abs/2006.13979) by Alexis Conneau, Alexei Baevski, Ronan Collobert, Abdelrahman Mohamed, Michael Auli.
+1. **[XLS-R](model_doc/xls_r)** (from Facebook AI) released with the paper [XLS-R: Self-supervised Cross-lingual Speech Representation Learning at Scale](https://arxiv.org/abs/2111.09296) by Arun Babu, Changhan Wang, Andros Tjandra, Kushal Lakhotia, Qiantong Xu, Naman Goyal, Kritika Singh, Patrick von Platen, Yatharth Saraf, Juan Pino, Alexei Baevski, Alexis Conneau, Michael Auli.
+1. **[YOSO](model_doc/yoso)** (from the University of Wisconsin - Madison) released with the paper [You Only Sample (Almost) Once: Linear Cost Self-Attention Via Bernoulli Sampling](https://arxiv.org/abs/2111.09714) by Zhanpeng Zeng, Yunyang Xiong, Sathya N. Ravi, Shailesh Acharya, Glenn Fung, Vikas Singh.
+
+
+### Frameworks aceitos
+
+A tabela abaixo representa a lista de suporte na biblioteca para cada um dos seguintes modelos, caso tenham um tokenizer
+do Python (chamado de "slow"), ou um tokenizer construído em cima da biblioteca 🤗 Tokenizers (chamado de "fast"). Além
+disso, são diferenciados pelo suporte em diferentes frameworks: JAX (por meio do Flax); PyTorch; e/ou Tensorflow.
+
+
+
+| Model | Tokenizer slow | Tokenizer fast | PyTorch support | TensorFlow support | Flax Support |
+|:---------------------------:|:--------------:|:--------------:|:---------------:|:------------------:|:------------:|
+| ALBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BEiT | ❌ | ❌ | ✅ | ❌ | ✅ |
+| BERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Bert Generation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| BigBird | ✅ | ✅ | ✅ | ❌ | ✅ |
+| BigBirdPegasus | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Blenderbot | ✅ | ✅ | ✅ | ✅ | ✅ |
+| BlenderbotSmall | ✅ | ✅ | ✅ | ✅ | ✅ |
+| CamemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Canine | ✅ | ❌ | ✅ | ❌ | ❌ |
+| CLIP | ✅ | ✅ | ✅ | ✅ | ✅ |
+| ConvBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ConvNext | ❌ | ❌ | ✅ | ✅ | ❌ |
+| CTRL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Data2VecAudio | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecText | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Data2VecVision | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeBERTa | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DeBERTa-v2 | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Decision Transformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DeiT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DETR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| DistilBERT | ✅ | ✅ | ✅ | ✅ | ✅ |
+| DPR | ✅ | ✅ | ✅ | ✅ | ❌ |
+| DPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ELECTRA | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| FairSeq Machine-Translation | ✅ | ❌ | ✅ | ❌ | ❌ |
+| FlauBERT | ✅ | ❌ | ✅ | ✅ | ❌ |
+| FNet | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Funnel Transformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| GLPN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| GPT Neo | ❌ | ❌ | ✅ | ❌ | ✅ |
+| GPT-J | ❌ | ❌ | ✅ | ✅ | ✅ |
+| Hubert | ❌ | ❌ | ✅ | ✅ | ❌ |
+| I-BERT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ImageGPT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| LayoutLM | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LayoutLMv2 | ✅ | ✅ | ✅ | ❌ | ❌ |
+| LED | ✅ | ✅ | ✅ | ✅ | ❌ |
+| Longformer | ✅ | ✅ | ✅ | ✅ | ❌ |
+| LUKE | ✅ | ❌ | ✅ | ❌ | ❌ |
+| LXMERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| M2M100 | ✅ | ❌ | ✅ | ❌ | ❌ |
+| Marian | ✅ | ❌ | ✅ | ✅ | ✅ |
+| MaskFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| mBART | ✅ | ✅ | ✅ | ✅ | ✅ |
+| MegatronBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| MobileBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| MPNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| mT5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Nystromformer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| OpenAI GPT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| OpenAI GPT-2 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Pegasus | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Perceiver | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PLBart | ✅ | ❌ | ✅ | ❌ | ❌ |
+| PoolFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| QDQBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| RAG | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Realm | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Reformer | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RegNet | ❌ | ❌ | ✅ | ✅ | ✅ |
+| RemBERT | ✅ | ✅ | ✅ | ✅ | ❌ |
+| ResNet | ❌ | ❌ | ✅ | ❌ | ✅ |
+| RetriBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| RoFormer | ✅ | ✅ | ✅ | ✅ | ✅ |
+| SegFormer | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW | ❌ | ❌ | ✅ | ❌ | ❌ |
+| SEW-D | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Speech Encoder decoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| Speech2Text | ✅ | ❌ | ✅ | ✅ | ❌ |
+| Speech2Text2 | ✅ | ❌ | ❌ | ❌ | ❌ |
+| Splinter | ✅ | ✅ | ✅ | ❌ | ❌ |
+| SqueezeBERT | ✅ | ✅ | ✅ | ❌ | ❌ |
+| Swin | ❌ | ❌ | ✅ | ❌ | ❌ |
+| T5 | ✅ | ✅ | ✅ | ✅ | ✅ |
+| TAPAS | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TAPEX | ✅ | ✅ | ✅ | ✅ | ✅ |
+| Transformer-XL | ✅ | ❌ | ✅ | ✅ | ❌ |
+| TrOCR | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeech | ❌ | ❌ | ✅ | ❌ | ❌ |
+| UniSpeechSat | ❌ | ❌ | ✅ | ❌ | ❌ |
+| VAN | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViLT | ❌ | ❌ | ✅ | ❌ | ❌ |
+| Vision Encoder decoder | ❌ | ❌ | ✅ | ✅ | ✅ |
+| VisionTextDualEncoder | ❌ | ❌ | ✅ | ❌ | ✅ |
+| VisualBert | ❌ | ❌ | ✅ | ❌ | ❌ |
+| ViT | ❌ | ❌ | ✅ | ✅ | ✅ |
+| ViTMAE | ❌ | ❌ | ✅ | ✅ | ❌ |
+| Wav2Vec2 | ✅ | ❌ | ✅ | ✅ | ✅ |
+| WavLM | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XGLM | ✅ | ✅ | ✅ | ❌ | ✅ |
+| XLM | ✅ | ❌ | ✅ | ✅ | ❌ |
+| XLM-RoBERTa | ✅ | ✅ | ✅ | ✅ | ✅ |
+| XLM-RoBERTa-XL | ❌ | ❌ | ✅ | ❌ | ❌ |
+| XLMProphetNet | ✅ | ❌ | ✅ | ❌ | ❌ |
+| XLNet | ✅ | ✅ | ✅ | ✅ | ❌ |
+| YOSO | ❌ | ❌ | ✅ | ❌ | ❌ |
+
+
diff --git a/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/installation.md b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/installation.md
new file mode 100644
index 0000000000000000000000000000000000000000..f548736589ac0d81bc7ebe2d73d60652ce03040b
--- /dev/null
+++ b/tasks/tasksmith-e0f68dd4420c/environment/source/docs/source/pt/installation.md
@@ -0,0 +1,262 @@
+
+
+# Guia de Instalação
+
+Neste guia poderá encontrar informações para a instalação do 🤗 Transformers para qualquer biblioteca de
+Machine Learning com a qual esteja a trabalhar. Além disso, poderá encontrar informações sobre como gerar cachês e
+configurar o 🤗 Transformers para execução em modo offline (opcional).
+
+🤗 Transformers foi testado com Python 3.6+, PyTorch 1.1.0+, TensorFlow 2.0+, e Flax. Para instalar a biblioteca de
+deep learning com que deseja trabalhar, siga as instruções correspondentes listadas a seguir:
+
+* [PyTorch](https://pytorch.org/get-started/locally/)
+* [TensorFlow 2.0](https://www.tensorflow.org/install/pip)
+* [Flax](https://flax.readthedocs.io/en/latest/)
+
+## Instalação pelo Pip
+
+É sugerido instalar o 🤗 Transformers num [ambiente virtual](https://docs.python.org/3/library/venv.html). Se precisar
+de mais informações sobre ambientes virtuais em Python, consulte este [guia](https://packaging.python.org/guides/installing-using-pip-and-virtual-environments/).
+Um ambiente virtual facilitará a manipulação e organização de projetos e evita problemas de compatibilidade entre dependências.
+
+Comece criando um ambiente virtual no diretório do seu projeto:
+
+```bash
+python -m venv .env
+```
+
+E para ativar o ambiente virtual:
+
+```bash
+source .env/bin/activate
+```
+
+Agora É possível instalar o 🤗 Transformers com o comando a seguir:
+
+```bash
+pip install transformers
+```
+
+Somente para a CPU, é possível instalar o 🤗 Transformers e a biblioteca de deep learning respectiva apenas numa linha.
+
+Por exemplo, para instalar o 🤗 Transformers e o PyTorch, digite:
+
+```bash
+pip install transformers[torch]
+```
+
+🤗 Transformers e TensorFlow 2.0:
+
+```bash
+pip install transformers[tf-cpu]
+```
+
+🤗 Transformers e Flax:
+
+```bash
+pip install transformers[flax]
+```
+
+Por último, verifique se o 🤗 Transformers foi instalado com sucesso usando o seguinte comando para baixar um modelo pré-treinado:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('we love you'))"
+```
+
+Em seguida, imprima um rótulo e sua pontuação:
+
+```bash
+[{'label': 'POSITIVE', 'score': 0.9998704791069031}]
+```
+
+## Instalação usando a fonte
+
+Para instalar o 🤗 Transformers a partir da fonte use o seguinte comando:
+
+```bash
+pip install git+https://github.com/huggingface/transformers
+```
+
+O comando acima instalará a versão `master` mais atual em vez da última versão estável. A versão `master` é útil para
+utilizar os últimos updates contidos em 🤗 Transformers. Por exemplo, um erro recente pode ter sido corrigido somente
+após a última versão estável, antes que houvesse um novo lançamento. No entanto, há a possibilidade que a versão `master` não esteja estável.
+A equipa trata de mantér a versão `master` operacional e a maioria dos erros são resolvidos em poucas horas ou dias.
+Se encontrar quaisquer problemas, por favor abra um [Issue](https://github.com/huggingface/transformers/issues) para que o
+mesmo possa ser corrigido o mais rápido possível.
+
+Verifique que o 🤗 Transformers está instalado corretamente usando o seguinte comando:
+
+```bash
+python -c "from transformers import pipeline; print(pipeline('sentiment-analysis')('I love you'))"
+```
+
+## Instalação editável
+
+Uma instalação editável será necessária caso desejas um dos seguintes:
+* Usar a versão `master` do código fonte.
+* Contribuir ao 🤗 Transformers e precisa testar mudanças ao código.
+
+Para tal, clone o repositório e instale o 🤗 Transformers com os seguintes comandos:
+
+```bash
+git clone https://github.com/huggingface/transformers.git
+cd transformers
+pip install -e .
+```
+
+Estes comandos vão ligar o diretório para o qual foi clonado o repositório ao caminho de bibliotecas do Python.
+O Python agora buscará dentro dos arquivos que foram clonados além dos caminhos normais da biblioteca.
+Por exemplo, se os pacotes do Python se encontram instalados no caminho `~/anaconda3/envs/main/lib/python3.7/site-packages/`,
+o Python também buscará módulos no diretório onde clonamos o repositório `~/transformers/`.
+
+
 +
 +
 +
 +
 +
 +
 +